Tag Archives: Amazon Machine Learning

Amazon Nova Multimodal Embeddings: State-of-the-art embedding model for agentic RAG and semantic search

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/amazon-nova-multimodal-embeddings-now-available-in-amazon-bedrock/

Today, we’re introducing Amazon Nova Multimodal Embeddings, a state-of-the-art multimodal embedding model for agentic retrieval-augmented generation (RAG) and semantic search applications, available in Amazon Bedrock. It is the first unified embedding model that supports text, documents, images, video, and audio through a single model to enable crossmodal retrieval with leading accuracy.

Embedding models convert textual, visual, and audio inputs into numerical representations called embeddings. These embeddings capture the meaning of the input in a way that AI systems can compare, search, and analyze, powering use cases such as semantic search and RAG.

Organizations are increasingly seeking solutions to unlock insights from the growing volume of unstructured data that is spread across text, image, document, video, and audio content. For example, an organization might have product images, brochures that contain infographics and text, and user-uploaded video clips. Embedding models are able to unlock value from unstructured data, however traditional models are typically specialized to handle one content type. This limitation drives customers to either build complex crossmodal embedding solutions or restrict themselves to use cases focused on a single content type. The problem also applies to mixed-modality content types such as documents with interleaved text and images or video with visual, audio, and textual elements where existing models struggle to capture crossmodal relationships effectively.

Nova Multimodal Embeddings supports a unified semantic space for text, documents, images, video, and audio for use cases such as crossmodal search across mixed-modality content, searching with a reference image, and retrieving visual documents.

Evaluating Amazon Nova Multimodal Embeddings performance
We evaluated the model on a broad range of benchmarks, and it delivers leading accuracy out-of-the-box as described in the following table.
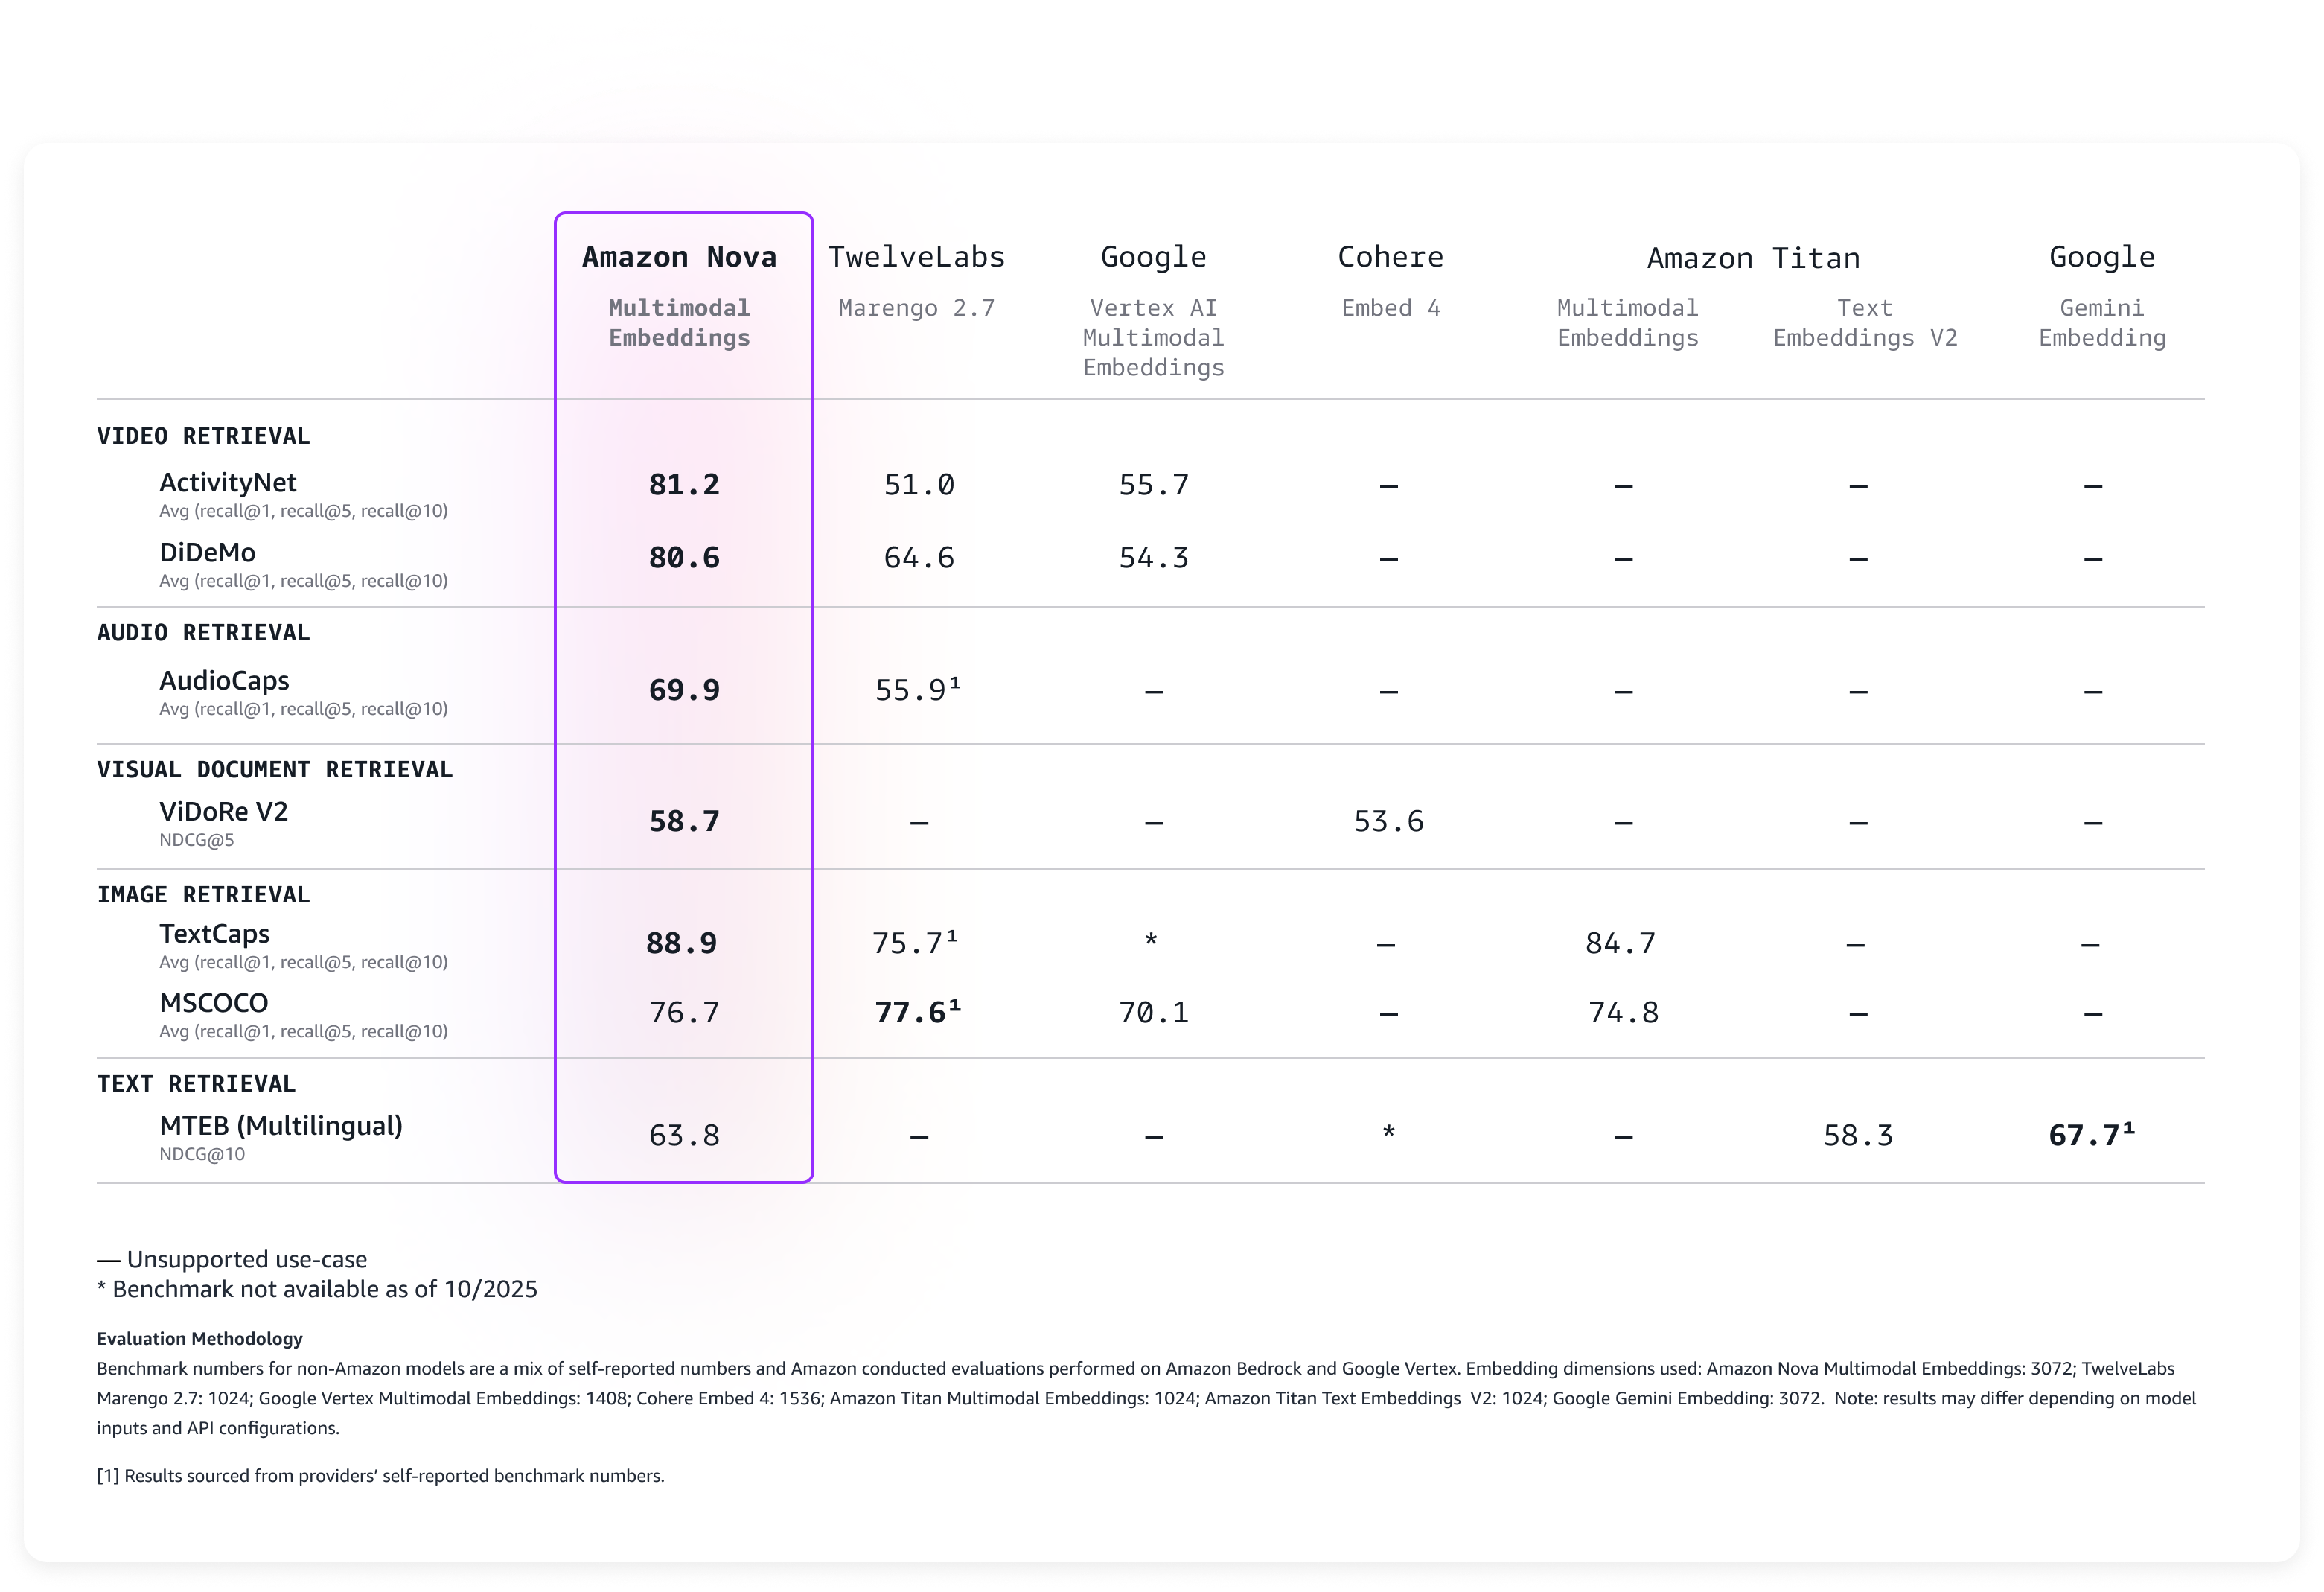
Amazon Nova Embeddings benchmarks

Nova Multimodal Embeddings supports a context length of up to 8K tokens, text in up to 200 languages, and accepts inputs via synchronous and asynchronous APIs. Additionally, it supports segmentation (also known as “chunking”) to partition long-form text, video, or audio content into manageable segments, generating embeddings for each portion. Lastly, the model offers four output embedding dimensions, trained using Matryoshka Representation Learning (MRL) that enables low-latency end-to-end retrieval with minimal accuracy changes.

Let’s see how the new model can be used in practice.

Using Amazon Nova Multimodal Embeddings
Getting started with Nova Multimodal Embeddings follows the same pattern as other models in Amazon Bedrock. The model accepts text, documents, images, video, or audio as input and returns numerical embeddings that you can use for semantic search, similarity comparison, or RAG.

Here’s a practical example using the AWS SDK for Python (Boto3) that shows how to create embeddings from different content types and store them for later retrieval. For simplicity, I’ll use Amazon S3 Vectors, a cost-optimized storage with native support for storing and querying vectors at any scale, to store and search the embeddings.

Let’s start with the fundamentals: converting text into embeddings. This example shows how to transform a simple text description into a numerical representation that captures its semantic meaning. These embeddings can later be compared with embeddings from documents, images, videos, or audio to find related content.

To make the code easy to follow, I’ll show a section of the script at a time. The full script is included at the end of this walkthrough.

import json
import base64
import time
import boto3

MODEL_ID = "amazon.nova-2-multimodal-embeddings-v1:0"
EMBEDDING_DIMENSION = 3072

# Initialize Amazon Bedrock Runtime client
bedrock_runtime = boto3.client("bedrock-runtime", region_name="us-east-1")

print(f"Generating text embedding with {MODEL_ID} ...")

# Text to embed
text = "Amazon Nova is a multimodal foundation model"

# Create embedding
request_body = {
    "taskType": "SINGLE_EMBEDDING",
    "singleEmbeddingParams": {
        "embeddingPurpose": "GENERIC_INDEX",
        "embeddingDimension": EMBEDDING_DIMENSION,
        "text": {"truncationMode": "END", "value": text},
    },
}

response = bedrock_runtime.invoke_model(
    body=json.dumps(request_body),
    modelId=MODEL_ID,
    contentType="application/json",
)

# Extract embedding
response_body = json.loads(response["body"].read())
embedding = response_body["embeddings"][0]["embedding"]

print(f"Generated embedding with {len(embedding)} dimensions")

Now we’ll process visual content using the same embedding space using a photo.jpg file in the same folder as the script. This demonstrates the power of multimodality: Nova Multimodal Embeddings is able to capture both textual and visual context into a single embedding that provides enhanced understanding of the document.

Nova Multimodal Embeddings can generate embeddings that are optimized for how they are being used. When indexing for a search or retrieval use case, embeddingPurpose can be set to GENERIC_INDEX. For the query step, embeddingPurpose can be set depending on the type of item to be retrieved. For example, when retrieving documents, embeddingPurpose can be set to DOCUMENT_RETRIEVAL.

# Read and encode image
print(f"Generating image embedding with {MODEL_ID} ...")

with open("photo.jpg", "rb") as f:
    image_bytes = base64.b64encode(f.read()).decode("utf-8")

# Create embedding
request_body = {
    "taskType": "SINGLE_EMBEDDING",
    "singleEmbeddingParams": {
        "embeddingPurpose": "GENERIC_INDEX",
        "embeddingDimension": EMBEDDING_DIMENSION,
        "image": {
            "format": "jpeg",
            "source": {"bytes": image_bytes}
        },
    },
}

response = bedrock_runtime.invoke_model(
    body=json.dumps(request_body),
    modelId=MODEL_ID,
    contentType="application/json",
)

# Extract embedding
response_body = json.loads(response["body"].read())
embedding = response_body["embeddings"][0]["embedding"]

print(f"Generated embedding with {len(embedding)} dimensions")

To process video content, I use the asynchronous API. That’s a requirement for videos that are larger than 25MB when encoded as Base64. First, I upload a local video to an S3 bucket in the same AWS Region.

aws s3 cp presentation.mp4 s3://my-video-bucket/videos/

This example shows how to extract embeddings from both visual and audio components of a video file. The segmentation feature breaks longer videos into manageable chunks, making it practical to search through hours of content efficiently.

# Initialize Amazon S3 client
s3 = boto3.client("s3", region_name="us-east-1")

print(f"Generating video embedding with {MODEL_ID} ...")

# Amazon S3 URIs
S3_VIDEO_URI = "s3://my-video-bucket/videos/presentation.mp4"
S3_EMBEDDING_DESTINATION_URI = "s3://my-embedding-destination-bucket/embeddings-output/"

# Create async embedding job for video with audio
model_input = {
    "taskType": "SEGMENTED_EMBEDDING",
    "segmentedEmbeddingParams": {
        "embeddingPurpose": "GENERIC_INDEX",
        "embeddingDimension": EMBEDDING_DIMENSION,
        "video": {
            "format": "mp4",
            "embeddingMode": "AUDIO_VIDEO_COMBINED",
            "source": {
                "s3Location": {"uri": S3_VIDEO_URI}
            },
            "segmentationConfig": {
                "durationSeconds": 15  # Segment into 15-second chunks
            },
        },
    },
}

response = bedrock_runtime.start_async_invoke(
    modelId=MODEL_ID,
    modelInput=model_input,
    outputDataConfig={
        "s3OutputDataConfig": {
            "s3Uri": S3_EMBEDDING_DESTINATION_URI
        }
    },
)

invocation_arn = response["invocationArn"]
print(f"Async job started: {invocation_arn}")

# Poll until job completes
print("\nPolling for job completion...")
while True:
    job = bedrock_runtime.get_async_invoke(invocationArn=invocation_arn)
    status = job["status"]
    print(f"Status: {status}")

    if status != "InProgress":
        break
    time.sleep(15)

# Check if job completed successfully
if status == "Completed":
    output_s3_uri = job["outputDataConfig"]["s3OutputDataConfig"]["s3Uri"]
    print(f"\nSuccess! Embeddings at: {output_s3_uri}")

    # Parse S3 URI to get bucket and prefix
    s3_uri_parts = output_s3_uri[5:].split("/", 1)  # Remove "s3://" prefix
    bucket = s3_uri_parts[0]
    prefix = s3_uri_parts[1] if len(s3_uri_parts) > 1 else ""

    # AUDIO_VIDEO_COMBINED mode outputs to embedding-audio-video.jsonl
    # The output_s3_uri already includes the job ID, so just append the filename
    embeddings_key = f"{prefix}/embedding-audio-video.jsonl".lstrip("/")

    print(f"Reading embeddings from: s3://{bucket}/{embeddings_key}")

    # Read and parse JSONL file
    response = s3.get_object(Bucket=bucket, Key=embeddings_key)
    content = response['Body'].read().decode('utf-8')

    embeddings = []
    for line in content.strip().split('\n'):
        if line:
            embeddings.append(json.loads(line))

    print(f"\nFound {len(embeddings)} video segments:")
    for i, segment in enumerate(embeddings):
        print(f"  Segment {i}: {segment.get('startTime', 0):.1f}s - {segment.get('endTime', 0):.1f}s")
        print(f"    Embedding dimension: {len(segment.get('embedding', []))}")
else:
    print(f"\nJob failed: {job.get('failureMessage', 'Unknown error')}")

With our embeddings generated, we need a place to store and search them efficiently. This example demonstrates setting up a vector store using Amazon S3 Vectors, which provides the infrastructure needed for similarity search at scale. Think of this as creating a searchable index where semantically similar content naturally clusters together. When adding an embedding to the index, I use the metadata to specify the original format and the content being indexed.

# Initialize Amazon S3 Vectors client
s3vectors = boto3.client("s3vectors", region_name="us-east-1")

# Configuration
VECTOR_BUCKET = "my-vector-store"
INDEX_NAME = "embeddings"

# Create vector bucket and index (if they don't exist)
try:
    s3vectors.get_vector_bucket(vectorBucketName=VECTOR_BUCKET)
    print(f"Vector bucket {VECTOR_BUCKET} already exists")
except s3vectors.exceptions.NotFoundException:
    s3vectors.create_vector_bucket(vectorBucketName=VECTOR_BUCKET)
    print(f"Created vector bucket: {VECTOR_BUCKET}")

try:
    s3vectors.get_index(vectorBucketName=VECTOR_BUCKET, indexName=INDEX_NAME)
    print(f"Vector index {INDEX_NAME} already exists")
except s3vectors.exceptions.NotFoundException:
    s3vectors.create_index(
        vectorBucketName=VECTOR_BUCKET,
        indexName=INDEX_NAME,
        dimension=EMBEDDING_DIMENSION,
        dataType="float32",
        distanceMetric="cosine"
    )
    print(f"Created index: {INDEX_NAME}")

texts = [
    "Machine learning on AWS",
    "Amazon Bedrock provides foundation models",
    "S3 Vectors enables semantic search"
]

print(f"\nGenerating embeddings for {len(texts)} texts...")

# Generate embeddings using Amazon Nova for each text
vectors = []
for text in texts:
    response = bedrock_runtime.invoke_model(
        body=json.dumps({
            "taskType": "SINGLE_EMBEDDING",
            "singleEmbeddingParams": {
                "embeddingDimension": EMBEDDING_DIMENSION,
                "text": {"truncationMode": "END", "value": text}
            }
        }),
        modelId=MODEL_ID,
        accept="application/json",
        contentType="application/json"
    )

    response_body = json.loads(response["body"].read())
    embedding = response_body["embeddings"][0]["embedding"]

    vectors.append({
        "key": f"text:{text[:50]}",  # Unique identifier
        "data": {"float32": embedding},
        "metadata": {"type": "text", "content": text}
    })
    print(f"  ✓ Generated embedding for: {text}")

# Add all vectors to store in a single call
s3vectors.put_vectors(
    vectorBucketName=VECTOR_BUCKET,
    indexName=INDEX_NAME,
    vectors=vectors
)

print(f"\nSuccessfully added {len(vectors)} vectors to the store in one put_vectors call!")

This final example demonstrates the capability of searching across different content types with a single query, finding the most similar content regardless of whether it originated from text, images, videos, or audio. The distance scores help you understand how closely related the results are to your original query.

# Text to query
query_text = "foundation models"  

print(f"\nGenerating embeddings for query '{query_text}' ...")

# Generate embeddings
response = bedrock_runtime.invoke_model(
    body=json.dumps({
        "taskType": "SINGLE_EMBEDDING",
        "singleEmbeddingParams": {
            "embeddingPurpose": "GENERIC_RETRIEVAL",
            "embeddingDimension": EMBEDDING_DIMENSION,
            "text": {"truncationMode": "END", "value": query_text}
        }
    }),
    modelId=MODEL_ID,
    accept="application/json",
    contentType="application/json"
)

response_body = json.loads(response["body"].read())
query_embedding = response_body["embeddings"][0]["embedding"]

print(f"Searching for similar embeddings...\n")

# Search for top 5 most similar vectors
response = s3vectors.query_vectors(
    vectorBucketName=VECTOR_BUCKET,
    indexName=INDEX_NAME,
    queryVector={"float32": query_embedding},
    topK=5,
    returnDistance=True,
    returnMetadata=True
)

# Display results
print(f"Found {len(response['vectors'])} results:\n")
for i, result in enumerate(response["vectors"], 1):
    print(f"{i}. {result['key']}")
    print(f"   Distance: {result['distance']:.4f}")
    if result.get("metadata"):
        print(f"   Metadata: {result['metadata']}")
    print()

Crossmodal search is one of the key advantages of multimodal embeddings. With crossmodal search, you can query with text and find relevant images. You can also search for videos using text descriptions, find audio clips that match certain topics, or discover documents based on their visual and textual content. For your reference, the full script with all previous examples merged together is here:

import json
import base64
import time
import boto3

MODEL_ID = "amazon.nova-2-multimodal-embeddings-v1:0"
EMBEDDING_DIMENSION = 3072

# Initialize Amazon Bedrock Runtime client
bedrock_runtime = boto3.client("bedrock-runtime", region_name="us-east-1")

print(f"Generating text embedding with {MODEL_ID} ...")

# Text to embed
text = "Amazon Nova is a multimodal foundation model"

# Create embedding
request_body = {
    "taskType": "SINGLE_EMBEDDING",
    "singleEmbeddingParams": {
        "embeddingPurpose": "GENERIC_INDEX",
        "embeddingDimension": EMBEDDING_DIMENSION,
        "text": {"truncationMode": "END", "value": text},
    },
}

response = bedrock_runtime.invoke_model(
    body=json.dumps(request_body),
    modelId=MODEL_ID,
    contentType="application/json",
)

# Extract embedding
response_body = json.loads(response["body"].read())
embedding = response_body["embeddings"][0]["embedding"]

print(f"Generated embedding with {len(embedding)} dimensions")
# Read and encode image
print(f"Generating image embedding with {MODEL_ID} ...")

with open("photo.jpg", "rb") as f:
    image_bytes = base64.b64encode(f.read()).decode("utf-8")

# Create embedding
request_body = {
    "taskType": "SINGLE_EMBEDDING",
    "singleEmbeddingParams": {
        "embeddingPurpose": "GENERIC_INDEX",
        "embeddingDimension": EMBEDDING_DIMENSION,
        "image": {
            "format": "jpeg",
            "source": {"bytes": image_bytes}
        },
    },
}

response = bedrock_runtime.invoke_model(
    body=json.dumps(request_body),
    modelId=MODEL_ID,
    contentType="application/json",
)

# Extract embedding
response_body = json.loads(response["body"].read())
embedding = response_body["embeddings"][0]["embedding"]

print(f"Generated embedding with {len(embedding)} dimensions")
# Initialize Amazon S3 client
s3 = boto3.client("s3", region_name="us-east-1")

print(f"Generating video embedding with {MODEL_ID} ...")

# Amazon S3 URIs
S3_VIDEO_URI = "s3://my-video-bucket/videos/presentation.mp4"

# Amazon S3 output bucket and location
S3_EMBEDDING_DESTINATION_URI = "s3://my-video-bucket/embeddings-output/"

# Create async embedding job for video with audio
model_input = {
    "taskType": "SEGMENTED_EMBEDDING",
    "segmentedEmbeddingParams": {
        "embeddingPurpose": "GENERIC_INDEX",
        "embeddingDimension": EMBEDDING_DIMENSION,
        "video": {
            "format": "mp4",
            "embeddingMode": "AUDIO_VIDEO_COMBINED",
            "source": {
                "s3Location": {"uri": S3_VIDEO_URI}
            },
            "segmentationConfig": {
                "durationSeconds": 15  # Segment into 15-second chunks
            },
        },
    },
}

response = bedrock_runtime.start_async_invoke(
    modelId=MODEL_ID,
    modelInput=model_input,
    outputDataConfig={
        "s3OutputDataConfig": {
            "s3Uri": S3_EMBEDDING_DESTINATION_URI
        }
    },
)

invocation_arn = response["invocationArn"]
print(f"Async job started: {invocation_arn}")

# Poll until job completes
print("\nPolling for job completion...")
while True:
    job = bedrock_runtime.get_async_invoke(invocationArn=invocation_arn)
    status = job["status"]
    print(f"Status: {status}")

    if status != "InProgress":
        break
    time.sleep(15)

# Check if job completed successfully
if status == "Completed":
    output_s3_uri = job["outputDataConfig"]["s3OutputDataConfig"]["s3Uri"]
    print(f"\nSuccess! Embeddings at: {output_s3_uri}")

    # Parse S3 URI to get bucket and prefix
    s3_uri_parts = output_s3_uri[5:].split("/", 1)  # Remove "s3://" prefix
    bucket = s3_uri_parts[0]
    prefix = s3_uri_parts[1] if len(s3_uri_parts) > 1 else ""

    # AUDIO_VIDEO_COMBINED mode outputs to embedding-audio-video.jsonl
    # The output_s3_uri already includes the job ID, so just append the filename
    embeddings_key = f"{prefix}/embedding-audio-video.jsonl".lstrip("/")

    print(f"Reading embeddings from: s3://{bucket}/{embeddings_key}")

    # Read and parse JSONL file
    response = s3.get_object(Bucket=bucket, Key=embeddings_key)
    content = response['Body'].read().decode('utf-8')

    embeddings = []
    for line in content.strip().split('\n'):
        if line:
            embeddings.append(json.loads(line))

    print(f"\nFound {len(embeddings)} video segments:")
    for i, segment in enumerate(embeddings):
        print(f"  Segment {i}: {segment.get('startTime', 0):.1f}s - {segment.get('endTime', 0):.1f}s")
        print(f"    Embedding dimension: {len(segment.get('embedding', []))}")
else:
    print(f"\nJob failed: {job.get('failureMessage', 'Unknown error')}")
# Initialize Amazon S3 Vectors client
s3vectors = boto3.client("s3vectors", region_name="us-east-1")

# Configuration
VECTOR_BUCKET = "my-vector-store"
INDEX_NAME = "embeddings"

# Create vector bucket and index (if they don't exist)
try:
    s3vectors.get_vector_bucket(vectorBucketName=VECTOR_BUCKET)
    print(f"Vector bucket {VECTOR_BUCKET} already exists")
except s3vectors.exceptions.NotFoundException:
    s3vectors.create_vector_bucket(vectorBucketName=VECTOR_BUCKET)
    print(f"Created vector bucket: {VECTOR_BUCKET}")

try:
    s3vectors.get_index(vectorBucketName=VECTOR_BUCKET, indexName=INDEX_NAME)
    print(f"Vector index {INDEX_NAME} already exists")
except s3vectors.exceptions.NotFoundException:
    s3vectors.create_index(
        vectorBucketName=VECTOR_BUCKET,
        indexName=INDEX_NAME,
        dimension=EMBEDDING_DIMENSION,
        dataType="float32",
        distanceMetric="cosine"
    )
    print(f"Created index: {INDEX_NAME}")

texts = [
    "Machine learning on AWS",
    "Amazon Bedrock provides foundation models",
    "S3 Vectors enables semantic search"
]

print(f"\nGenerating embeddings for {len(texts)} texts...")

# Generate embeddings using Amazon Nova for each text
vectors = []
for text in texts:
    response = bedrock_runtime.invoke_model(
        body=json.dumps({
            "taskType": "SINGLE_EMBEDDING",
            "singleEmbeddingParams": {
                "embeddingPurpose": "GENERIC_INDEX",
                "embeddingDimension": EMBEDDING_DIMENSION,
                "text": {"truncationMode": "END", "value": text}
            }
        }),
        modelId=MODEL_ID,
        accept="application/json",
        contentType="application/json"
    )

    response_body = json.loads(response["body"].read())
    embedding = response_body["embeddings"][0]["embedding"]

    vectors.append({
        "key": f"text:{text[:50]}",  # Unique identifier
        "data": {"float32": embedding},
        "metadata": {"type": "text", "content": text}
    })
    print(f"  ✓ Generated embedding for: {text}")

# Add all vectors to store in a single call
s3vectors.put_vectors(
    vectorBucketName=VECTOR_BUCKET,
    indexName=INDEX_NAME,
    vectors=vectors
)

print(f"\nSuccessfully added {len(vectors)} vectors to the store in one put_vectors call!")
# Text to query
query_text = "foundation models"  

print(f"\nGenerating embeddings for query '{query_text}' ...")

# Generate embeddings
response = bedrock_runtime.invoke_model(
    body=json.dumps({
        "taskType": "SINGLE_EMBEDDING",
        "singleEmbeddingParams": {
            "embeddingPurpose": "GENERIC_RETRIEVAL",
            "embeddingDimension": EMBEDDING_DIMENSION,
            "text": {"truncationMode": "END", "value": query_text}
        }
    }),
    modelId=MODEL_ID,
    accept="application/json",
    contentType="application/json"
)

response_body = json.loads(response["body"].read())
query_embedding = response_body["embeddings"][0]["embedding"]

print(f"Searching for similar embeddings...\n")

# Search for top 5 most similar vectors
response = s3vectors.query_vectors(
    vectorBucketName=VECTOR_BUCKET,
    indexName=INDEX_NAME,
    queryVector={"float32": query_embedding},
    topK=5,
    returnDistance=True,
    returnMetadata=True
)

# Display results
print(f"Found {len(response['vectors'])} results:\n")
for i, result in enumerate(response["vectors"], 1):
    print(f"{i}. {result['key']}")
    print(f"   Distance: {result['distance']:.4f}")
    if result.get("metadata"):
        print(f"   Metadata: {result['metadata']}")
    print()

For production applications, embeddings can be stored in any vector database. Amazon OpenSearch Service offers native integration with Nova Multimodal Embeddings at launch, making it straightforward to build scalable search applications. As shown in the examples before, Amazon S3 Vectors provides a simple way to store and query embeddings with your application data.

Things to know
Nova Multimodal Embeddings offers four output dimension options: 3,072, 1,024, 384, and 256. Larger dimensions provide more detailed representations but require more storage and computation. Smaller dimensions offer a practical balance between retrieval performance and resource efficiency. This flexibility helps you optimize for your specific application and cost requirements.

The model handles substantial context lengths. For text inputs, it can process up to 8,192 tokens at once. Video and audio inputs support segments of up to 30 seconds, and the model can segment longer files. This segmentation capability is particularly useful when working with large media files—the model splits them into manageable pieces and creates embeddings for each segment.

The model includes responsible AI features built into Amazon Bedrock. Content submitted for embedding goes through Amazon Bedrock content safety filters, and the model includes fairness measures to reduce bias.

As described in the code examples, the model can be invoked through both synchronous and asynchronous APIs. The synchronous API works well for real-time applications where you need immediate responses, such as processing user queries in a search interface. The asynchronous API handles latency insensitive workloads more efficiently, making it suitable for processing large content such as videos.

Availability and pricing
Amazon Nova Multimodal Embeddings is available today in Amazon Bedrock in the US East (N. Virginia) AWS Region. For detailed pricing information, visit the Amazon Bedrock pricing page.

To learn more, see the Amazon Nova User Guide for comprehensive documentation and the Amazon Nova model cookbook on GitHub for practical code examples.

If you’re using an AI–powered assistant for software development such as Amazon Q Developer or Kiro, you can set up the AWS API MCP Server to help the AI assistants interact with AWS services and resources and the AWS Knowledge MCP Server to provide up-to-date documentation, code samples, knowledge about the regional availability of AWS APIs and CloudFormation resources.

Start building multimodal AI-powered applications with Nova Multimodal Embeddings today, and share your feedback through AWS re:Post for Amazon Bedrock or your usual AWS Support contacts.

Danilo

Introducing Claude Sonnet 4.5 in Amazon Bedrock: Anthropic’s most intelligent model, best for coding and complex agents

Post Syndicated from Matheus Guimaraes original https://aws.amazon.com/blogs/aws/introducing-claude-sonnet-4-5-in-amazon-bedrock-anthropics-most-intelligent-model-best-for-coding-and-complex-agents/

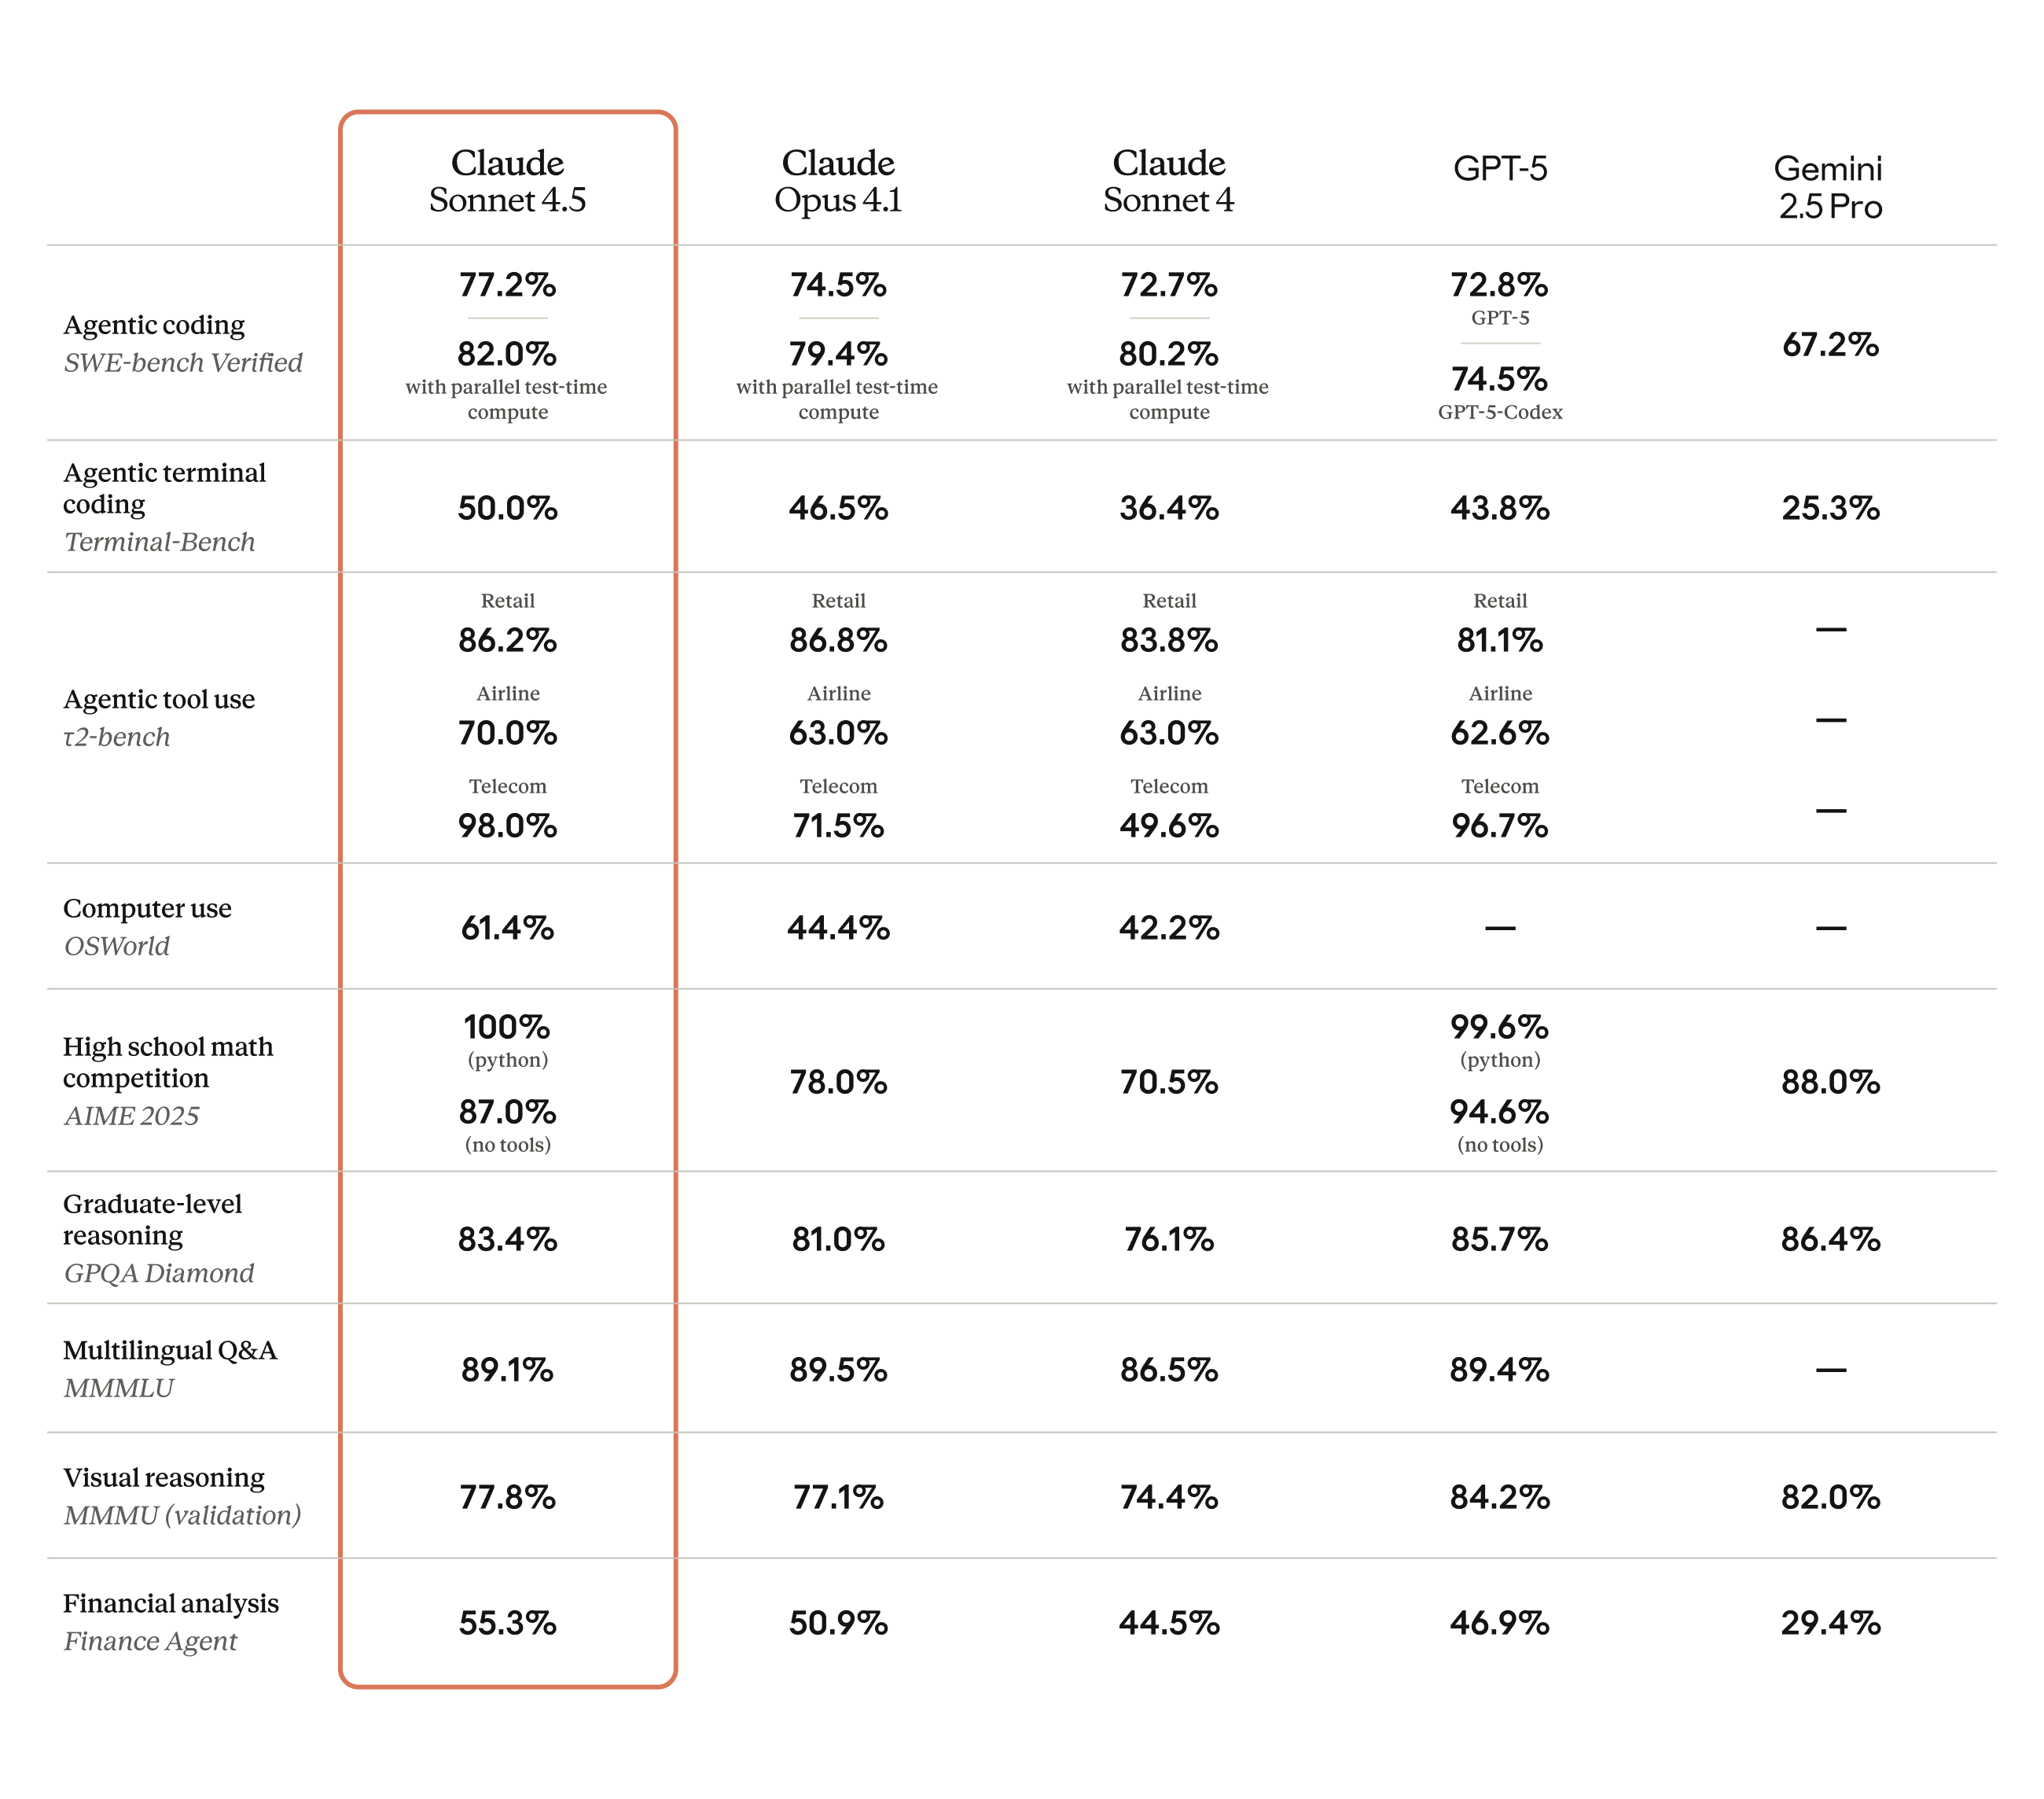
Today, we’re excited to announce that Claude Sonnet 4.5, powered by Anthropic, is now available in Amazon Bedrock, a fully managed service that offers a choice of high- performing foundation models from leading AI companies. This new model builds upon Claude 4’s foundation to achieve state-of-the-art performance in coding and complex agentic applications.

Claude Sonnet 4.5 demonstrates advancements in agent capabilities, with enhanced performance in tool handling, memory management, and context processing. The model shows marked improvements in code generation and analysis, from identifying optimal improvements to exercising stronger judgment in refactoring decisions. It particularly excels at autonomous long-horizon coding tasks, where it can effectively plan and execute complex software projects spanning hours or days while maintaining consistent performance and reliability throughout the development cycle.

By using Claude Sonnet 4.5 in Amazon Bedrock, developers gain access to a fully managed service that not only provides a unified API for foundation models but ensures their data stays under complete control with enterprise-grade tools for security, and optimization.

Claude Sonnet 4.5 also seamlessly integrates with Amazon Bedrock AgentCore, enabling developers to maximize the model’s capabilities for building complex agents. AgentCore’s purpose-built infrastructure complements the model’s enhanced abilities in tool handling, memory management, and context understanding. Developers can leverage complete session isolation, 8-hour long-running support, and comprehensive observability features to deploy and monitor production-ready agents from autonomous security operations to complex enterprise workflows.

Business applications and use cases
Beyond its technical capabilities, Sonnet 4.5 delivers practical business value through consistent performance and advanced problem-solving abilities. The model excels at producing and editing business documents while maintaining reliable performance across complex workflows.

The model demonstrates strength in several key industries:

  • Cybersecurity – Claude Sonnet 4.5 can be used to deploy agents that autonomously patch vulnerabilities before exploitation, shifting from reactive detection to proactive defense.
  • Finance – Sonnet 4.5 handles everything from entry-level financial analysis to advanced predictive analysis, helping transform manual audit preparation into intelligent risk management.
  • Research – Sonnet 4.5 can better handle tools, context, and deliver ready-to-go office files to drive expert analysis into final deliverables and actionable insights.

Sonnet 4.5 features in the Amazon Bedrock API
Here are some highlights of Sonnet 4.5 in the Amazon Bedrock API:

Smart Context Window Management – The new API introduces intelligent handling when AI models reach their maximum capacity. Instead of returning errors when conversations get too long, Claude Sonnet 4.5 will now generate responses up to the available limit and clearly indicate why it stopped. This eliminates frustrating interruptions and allows users to maximize their available context window.

Tool Use Clearing for Efficiency – Claude Sonnet 4.5 enables automatic cleanup of tool interaction history during long conversations. When conversations involve multiple tool calls, the system can automatically remove older tool results while preserving recent ones. This keeps conversations efficient and prevents unnecessary token consumption, reducing costs while maintaining conversation quality.

Cross-Conversation Memory – A new memory capability enables Sonnet 4.5 to remember information across different conversations through the use of a local memory file. Users can explicitly ask the model to remember preferences, context, or important information that persists beyond a single chat session. This creates more personalized and contextually aware interactions while keeping the information safe within the local file.

With these new capabilities for managing context, developers can build AI agents capable of handling long-running tasks at higher intelligence without hitting context limits or losing critical information as frequently.

Getting started
To begin working with Claude Sonnet 4.5, you can access it through Amazon Bedrock using the correct model ID. A good practice is to use the Amazon Bedrock Converse API to write code once and seamlessly switch between different models, making it easier to experiment with Sonnet 4.5 or any of the other models available in Amazon Bedrock.

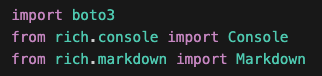
Let’s see this in action with a simple example. I’m going to use the Amazon Bedrock Converse API to send a prompt to Sonnet 4.5. I start by importing the modules I’m going to use. For this short example, I only need AWS SDK for Python (Boto3) so I can create a BedrockRuntimeClient. I’m also importing the rich package so I can format my output nicely later on.

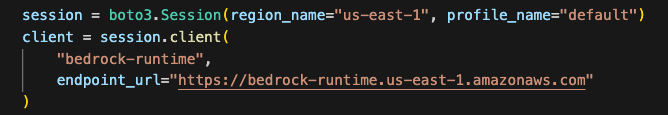
Following best practices, I create a boto3 session and create an Amazon Bedrock client from it instead of creating one directly. This gives you explicit control over configuration, improves thread safety, and makes your code more predictable and testable compared to relying on the default session.

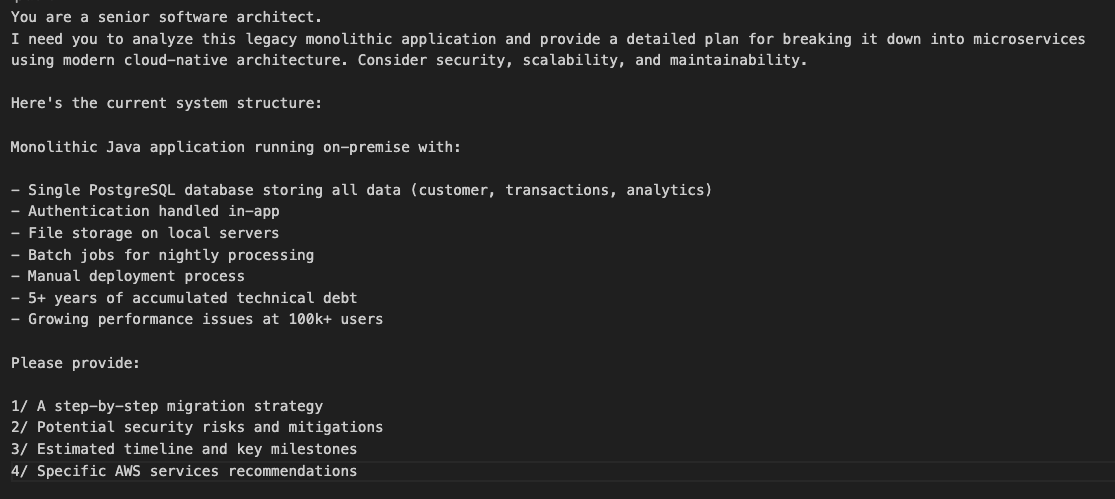
I want to give the model something with a bit of complexity instead of asking a simple question to demonstrate the power of Sonnet 4.5. So I’m going to give the model the current state of an imaginary legacy monolithic application written in Java with a single database and ask for a digital transformation plan which includes a migration strategy, risk assessment, estimated timeline and key milestones and specific AWS services recommendations.

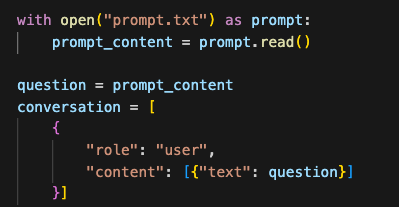
Because the prompt is quite long I put it in a text file locally and just load it up in code. I then set up the Amazon Bedrock converse payload setting the role to “user” to indicate that this is a message by the user of the application and add the prompt to the content.

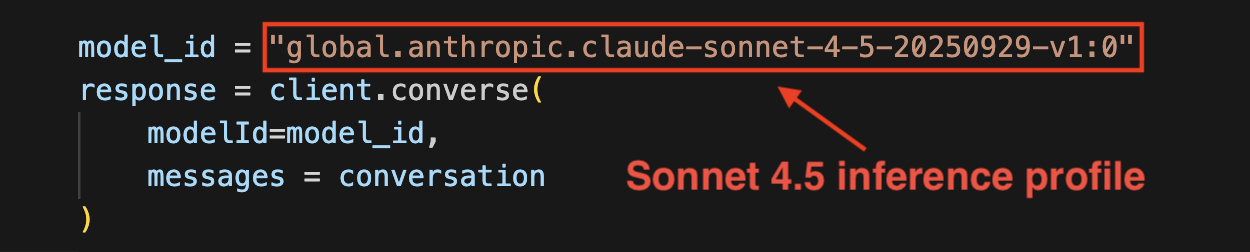
This is where the magic happens! We put it all together and call Claude Sonnet 4.5 using its model ID. Well, kind of. You can only access Sonnet 4.5 through an inference profile. This defines which AWS Regions will process your model requests and helps manage throughput and performance.

For this demo, I’ll be using one of Amazon Bedrock’s system-defined cross-Region inference profiles, which automatically routes requests across multiple Regions for optimal performance.

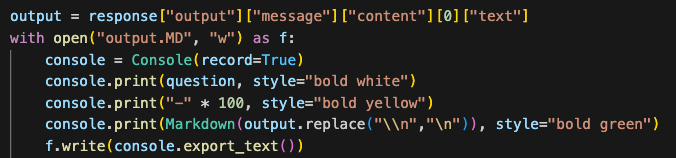
Now I just need to print to the screen to see the results. This is where I use the rich package I imported earlier just so we may have a nicely formatted output as I’m expecting a long response for this one. I also save the output to a file so I can have it handy as something to share with my teams.

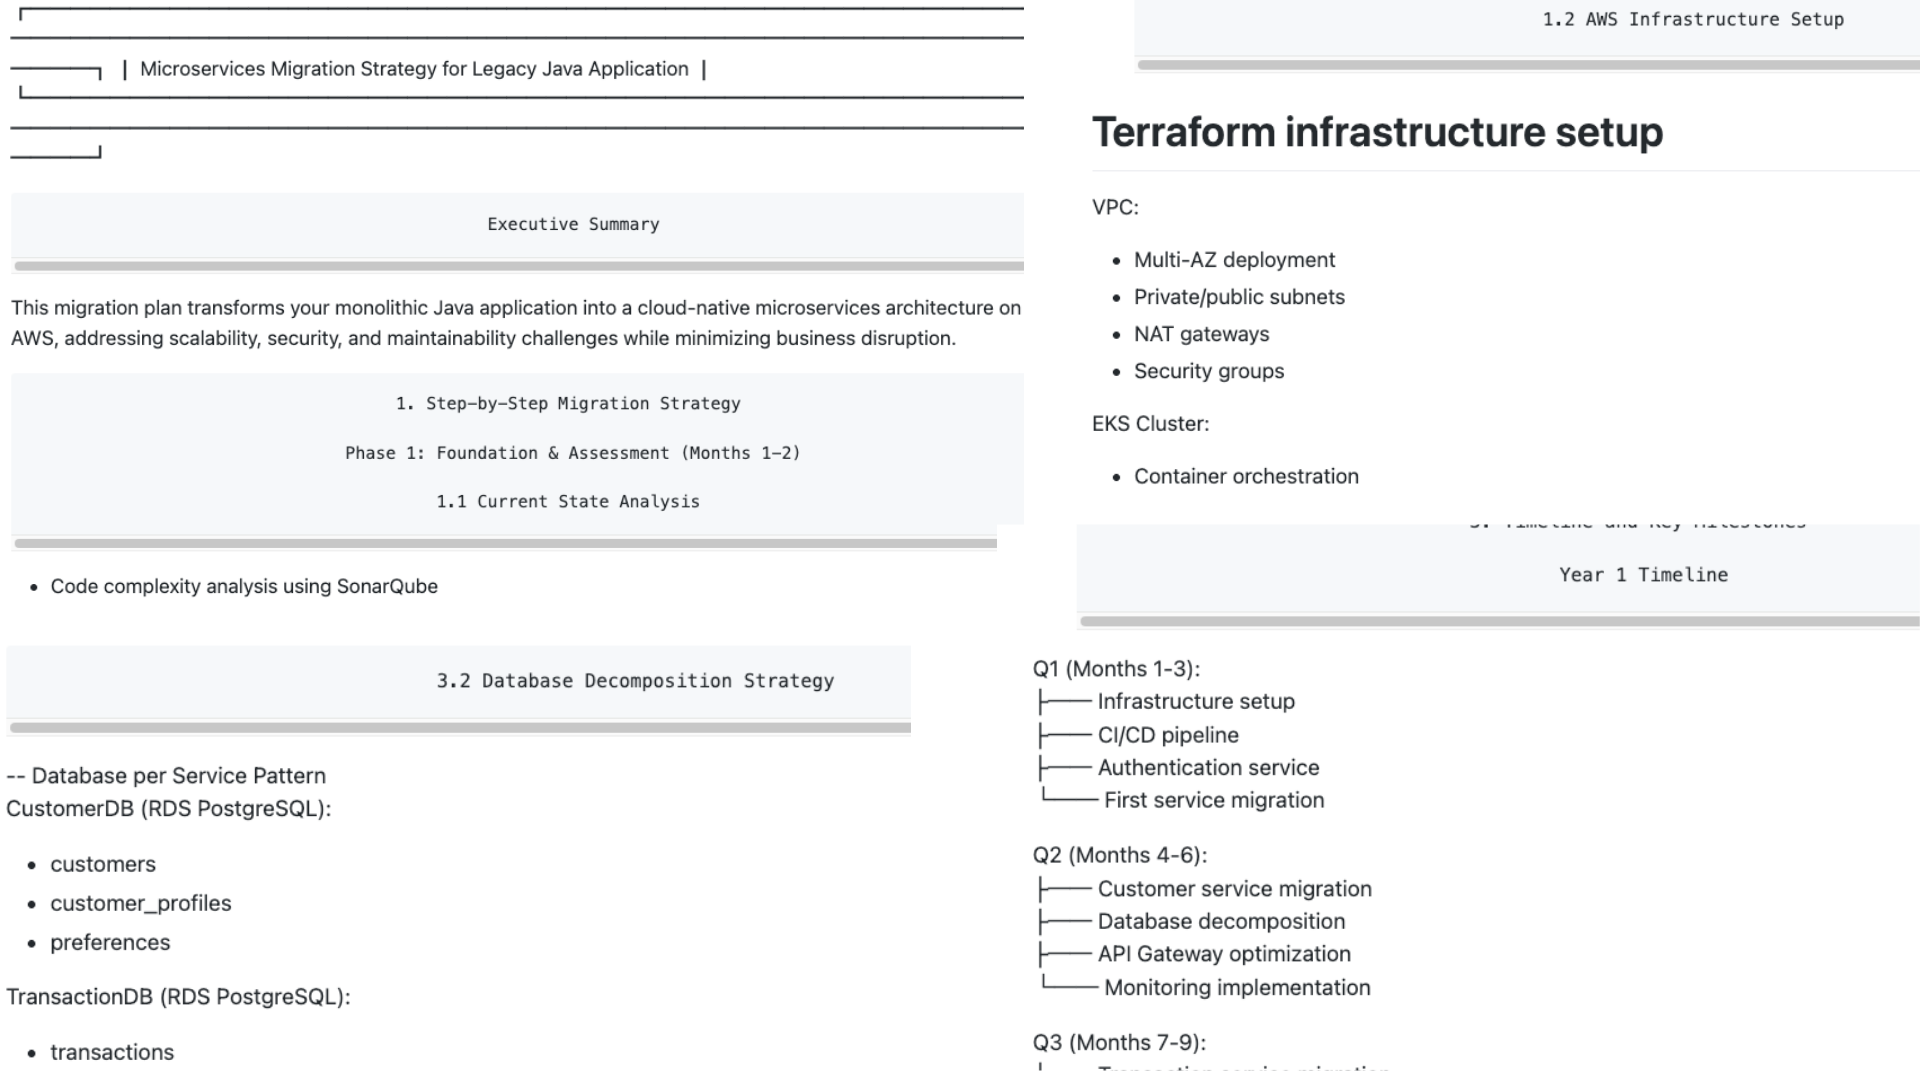
Ok, let’s check the results! As expected, Sonnet 4.5 worked through my requirements and provided extensive and deep guidance for my digital transformation plan that I could start putting into practice. It included an executive summary, a step-by-step migration strategy split into phases with time estimates, and even some code samples to seed the development process and start breaking things down into microservices. It also provided the business cases for introducing technology and recommended the correct AWS services for each scenario. Here are some highlights from the report.

Claude Sonnet 4.5 is able to maintain consistency while delivering creative solutions making it an ideal choice for businesses seeking to use AI for complex problem-solving and development tasks. Its enhanced capabilities in following directions and using tools effectively translate into more reliable and innovative solutions across various business contexts.

Things to know
Claude Sonnet 4.5 represents a significant step forward in agent capabilities, particularly excelling in areas where consistent performance and creative problem-solving are essential. Its enhanced abilities in tool handling, memory management, and context processing make it particularly valuable across key industries such as finance, research, and cybersecurity. Whether handling complex development lifecycles, executing long-running tasks, or tackling business-critical workflows, Claude Sonnet 4.5 combines technical excellence with practical business value.

Claude Sonnet 4.5 is available today. For detailed information about its availability please visit the documentation.

To learn more about Amazon Bedrock explore our self-paced Amazon Bedrock Workshop and discover how to use available models and their capabilities in your applications.

Qwen models are now available in Amazon Bedrock

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/qwen-models-are-now-available-in-amazon-bedrock/

Today we are adding Qwen models from Alibaba in Amazon Bedrock. With this launch, Amazon Bedrock continues to expand model choice by adding access to Qwen3 open weight foundation models (FMs) in a full managed, serverless way. This release includes four models: Qwen3-Coder-480B-A35B-Instruct, Qwen3-Coder-30B-A3B-Instruct, Qwen3-235B-A22B-Instruct-2507, and Qwen3-32B (Dense). Together, these models feature both mixture-of-experts (MoE) and dense architectures, providing flexible options for different application requirements.

Amazon Bedrock provides access to industry-leading FMs through a unified API without requiring infrastructure management. You can access models from multiple model providers, integrate models into your applications, and scale usage based on workload requirements. With Amazon Bedrock, customer data is never used to train the underlying models. With the addition of Qwen3 models, Amazon Bedrock offers even more options for use cases like:

  • Code generation and repository analysis with extended context understanding
  • Building agentic workflows that orchestrate multiple tools and APIs for business automation
  • Balancing AI costs and performance using hybrid thinking modes for adaptive reasoning

Qwen3 models in Amazon Bedrock
These four Qwen3 models are now available in Amazon Bedrock, each optimized for different performance and cost requirements:

  • Qwen3-Coder-480B-A35B-Instruct – This is a mixture-of-experts (MoE) model with 480B total parameters and 35B active parameters. It’s optimized for coding and agentic tasks and achieves strong results in benchmarks such as agentic coding, browser use, and tool use. These capabilities make it suitable for repository-scale code analysis and multistep workflow automation.
  • Qwen3-Coder-30B-A3B-Instruct – This is a MoE model with 30B total parameters and 3B active parameters. Specifically optimized for coding tasks and instruction-following scenarios, this model demonstrates strong performance in code generation, analysis, and debugging across multiple programming languages.
  • Qwen3-235B-A22B-Instruct-2507 – This is an instruction-tuned MoE model with 235B total parameters and 22B active parameters. It delivers competitive performance across coding, math, and general reasoning tasks, balancing capability with efficiency.
  • Qwen3-32B (Dense) – This is a dense model with 32B parameters. It is suitable for real-time or resource-constrained environments such as mobile devices and edge computing deployments where consistent performance is critical.

Architectural and functional features in Qwen3
The Qwen3 models introduce several architectural and functional features:

MoE compared with dense architectures – MoE models such as Qwen3-Coder-480B-A35B, Qwen3-Coder-30B-A3B-Instruct, and Qwen3-235B-A22B-Instruct-2507, activate only part of the parameters for each request, providing high performance with efficient inference. The dense Qwen3-32B activates all parameters, offering more consistent and predictable performance.

Agentic capabilities – Qwen3 models can handle multi-step reasoning and structured planning in one model invocation. They can generate outputs that call external tools or APIs when integrated into an agent framework. The models also maintain extended context across long sessions. In addition, they support tool calling to allow standardized communication with external environments.

Hybrid thinking modes – Qwen3 introduces a hybrid approach to problem-solving, which supports two modes: thinking and non-thinking. The thinking mode applies step-by-step reasoning before delivering the final answer. This is ideal for complex problems that require deeper thought. Whereas the non-thinking mode provides fast and near-instant responses for less complex tasks where speed is more important than depth. This helps developers manage performance and cost trade-offs more effectively.

Long-context handling – The Qwen3-Coder models support extended context windows, with up to 256K tokens natively and up to 1 million tokens with extrapolation methods. This allows the model to process entire repositories, large technical documents, or long conversational histories within a single task.

When to use each model
The four Qwen3 models serve distinct use cases. Qwen3-Coder-480B-A35B-Instruct is designed for complex software engineering scenarios. It’s suited for advanced code generation, long-context processing such as repository-level analysis, and integration with external tools. Qwen3-Coder-30B-A3B-Instruct is particularly effective for tasks such as code completion, refactoring, and answering programming-related queries. If you need versatile performance across multiple domains, Qwen3-235B-A22B-Instruct-2507 offers a balance, delivering strong general-purpose reasoning and instruction-following capabilities while leveraging the efficiency advantages of its MoE architecture. Qwen3-32B (Dense) is appropriate for scenarios where consistent performance, low latency, and cost optimization are important.

Getting started with Qwen models in Amazon Bedrock
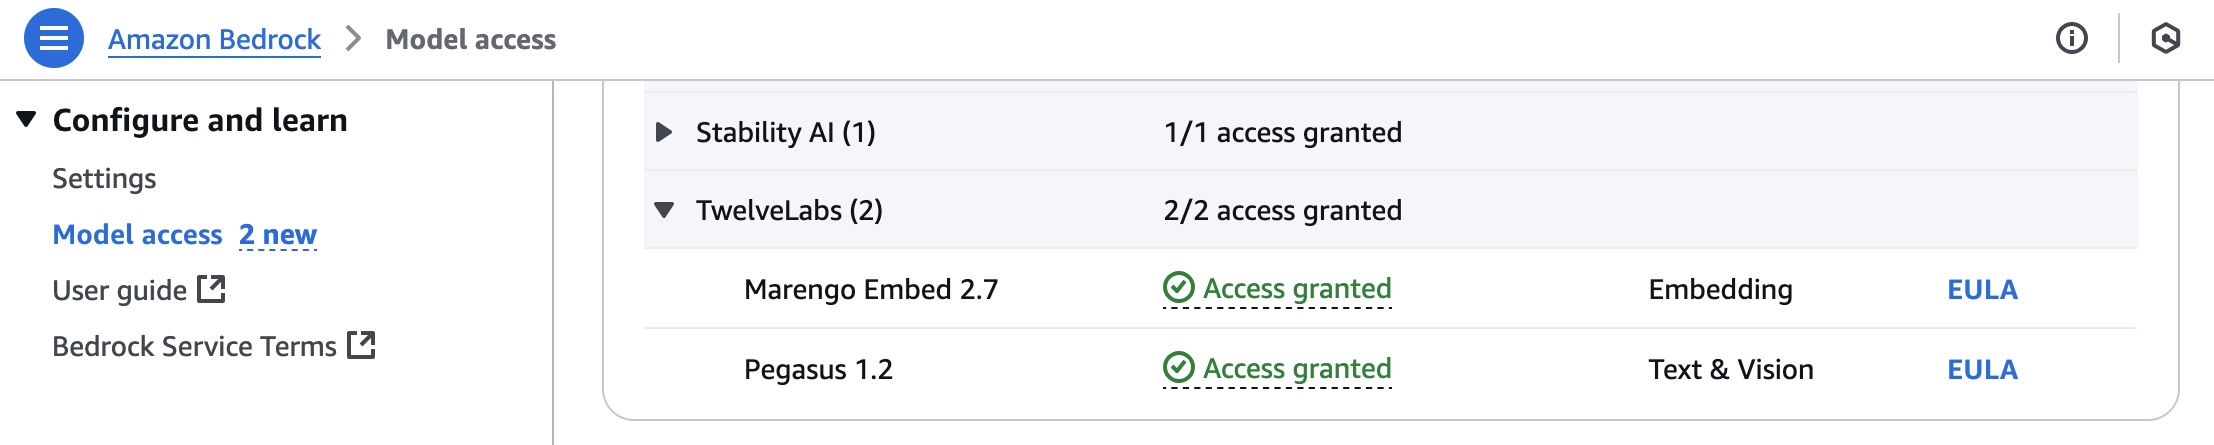
To begin using Qwen models, in the Amazon Bedrock console, I choose Model Access from the Configure and learn section of the navigation pane. I then navigate to the Qwen models to request access. In the Chat/Text Playground section of the navigation pane, I can quickly test the new Qwen models with my prompts.

To integrate Qwen3 models into my applications, I can use any AWS SDKs. The AWS SDKs include access to the Amazon Bedrock InvokeModel and Converse API. I can also use these model with any agentic framework that supports Amazon Bedrock and deploy the agents using Amazon Bedrock AgentCore. For example, here’s the Python code of a simple agent with tool access built using Strands Agents:

from strands import Agent
from strands_tools import calculator

agent = Agent(
    model="qwen.qwen3-coder-480b-instruct-v1:0",
    tools=[calculator]
)

agent("Tell me the square root of 42 ^ 9")

with open("function.py", 'r') as f:
    my_function_code = f.read()

agent(f"Help me optimize this Python function for better performance:\n\n{my_function_code}")

Now available
Qwen models are available today in the following AWS Regions:

  • Qwen3-Coder-480B-A35B-Instruct is available in the US West (Oregon), Asia Pacific (Mumbai, Tokyo), and Europe (London, Stockholm) Regions.
  • Qwen3-Coder-30B-A3B-Instruct, Qwen3-235B-A22B-Instruct-2507, and Qwen3-32B are available in the US East (N. Virginia), US West (Oregon), Asia Pacific (Mumbai, Tokyo), Europe (Ireland, London, Milan, Stockholm), and South America (São Paulo) Regions.

Check the full Region list for future updates. You can start testing and building immediately without infrastructure setup or capacity planning. To learn more, visit the Qwen in Amazon Bedrock product page and the Amazon Bedrock pricing page.

Try Qwen models on the Amazon Bedrock console now, and offer feedback through AWS re:Post for Amazon Bedrock or your typical AWS Support channels.

Danilo

DeepSeek-V3.1 model now available in Amazon Bedrock

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/deepseek-v3-1-now-available-in-amazon-bedrock/

In March, Amazon Web Services (AWS) became the first cloud service provider to deliver DeepSeek-R1 in a serverless way by launching it as a fully managed, generally available model in Amazon Bedrock. Since then, customers have used DeepSeek-R1’s capabilities through Amazon Bedrock to build generative AI applications, benefiting from the Bedrock’s robust guardrails and comprehensive tooling for safe AI deployment.

Today, I am excited to announce DeepSeek-V3.1 is now available as a fully managed foundation model in Amazon Bedrock. DeepSeek-V3.1 is a hybrid open weight model that switches between thinking mode (chain-of-thought reasoning) for detailed step-by-step analysis and non-thinking mode (direct answers) for faster responses.

According to DeepSeek, the thinking mode of DeepSeek-V3.1 achieves comparable answer quality with better results, stronger multi-step reasoning for complex search tasks, and big gains in thinking efficiency compared with DeepSeek-R1-0528.

Benchmarks DeepSeek-V3.1 DeepSeek-R1-0528
Browsecomp 30.0 8.9
Browsecomp_zh 49.2 35.7
HLE 29.8 24.8
xbench-DeepSearch 71.2 55.0
Frames 83.7 82.0
SimpleQA 93.4 92.3
Seal0 42.6 29.7
SWE-bench Verified 66.0 44.6
SWE-bench Multilingual 54.5 30.5
Terminal-Bench 31.3 5.7
(c)
https://api-docs.deepseek.com/news/news250821

DeepSeek-V3.1 model performance in tool usage and agent tasks has significantly improved through post-training optimization compared to previous DeepSeek models. DeepSeek-V3.1 also supports over 100 languages with near-native proficiency, including significantly improved capability in low-resource languages lacking large monolingual or parallel corpora. You can build global applications to deliver enhanced accuracy and reduced hallucinations compared to previous DeepSeek models, while maintaining visibility into its decision-making process.

Here are your key use cases using this model:

  • Code generation – DeepSeek-V3.1 excels in coding tasks with improvements in software engineering benchmarks and code agent capabilities, making it ideal for automated code generation, debugging, and software engineering workflows. It performs well on coding benchmarks while delivering high-quality results efficiently.
  • Agentic AI tools – The model features enhanced tool calling through post-training optimization, making it strong in tool usage and agentic workflows. It supports structured tool calling, code agents, and search agents, positioning it as a solid choice for building autonomous AI systems.
  • Enterprise applications – DeepSeek models are integrated into various chat platforms and productivity tools, enhancing user interactions and supporting customer service workflows. The model’s multilingual capabilities and cultural sensitivity make it suitable for global enterprise applications.

As I mentioned in my previous post, when implementing publicly available models, give careful consideration to data privacy requirements when implementing in your production environments, check for bias in output, and monitor your results in terms of data security, responsible AI, and model evaluation.

You can access the enterprise-grade security features of Amazon Bedrock and implement safeguards customized to your application requirements and responsible AI policies with Amazon Bedrock Guardrails. You can also evaluate and compare models to identify the optimal model for your use cases by using Amazon Bedrock model evaluation tools.

Get started with the DeepSeek-V3.1 model in Amazon Bedrock
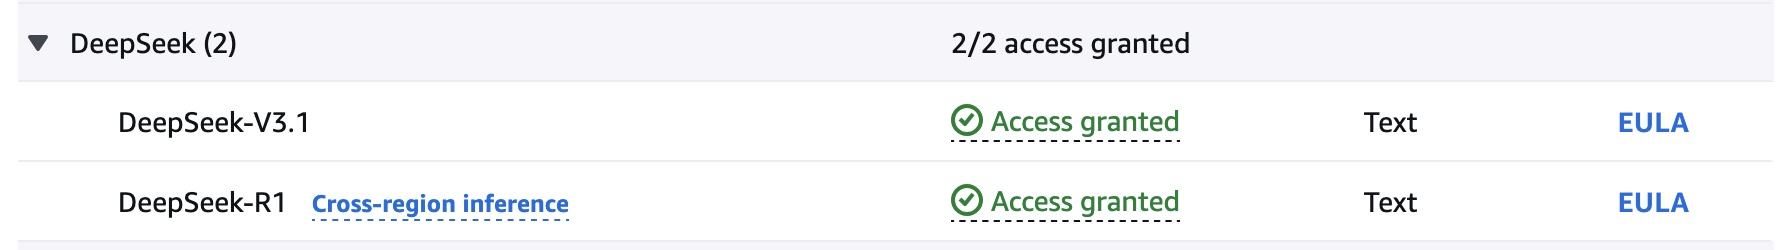
If you’re new to using the DeepSeek-V3.1 model, go to the Amazon Bedrock console, choose Model access under Bedrock configurations in the left navigation pane. To access the fully managed DeepSeek-V3.1 model, request access for DeepSeek-V3.1 in the DeepSeek section. You’ll then be granted access to the model in Amazon Bedrock.

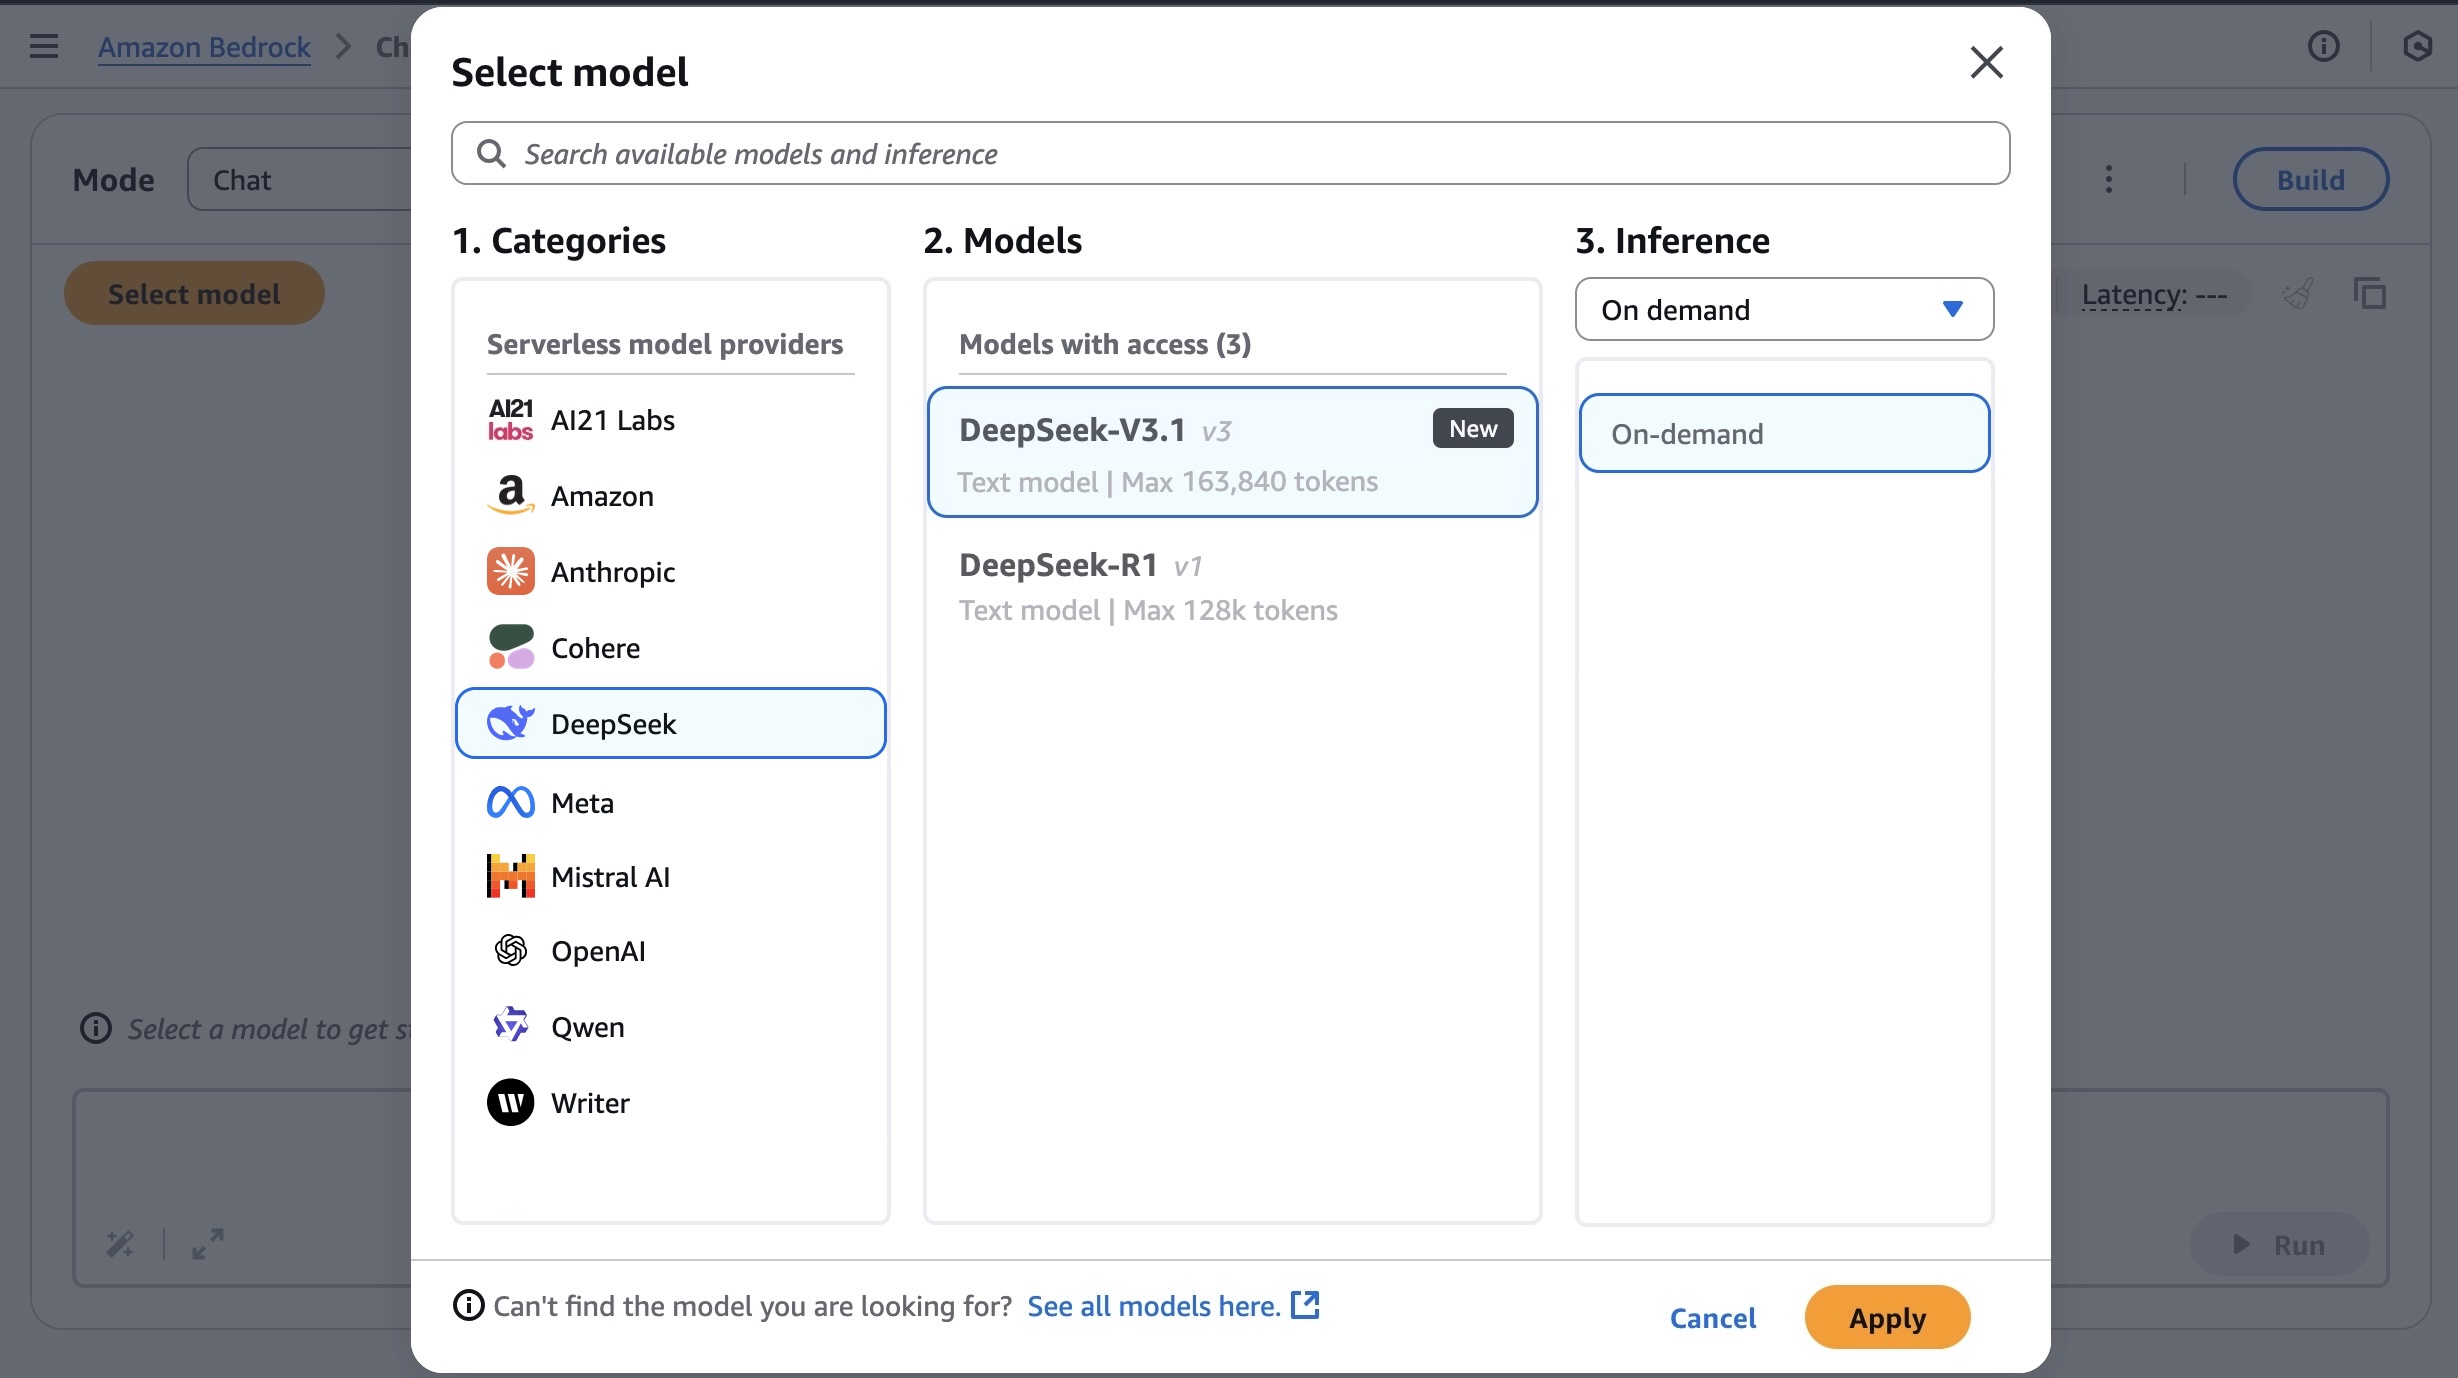
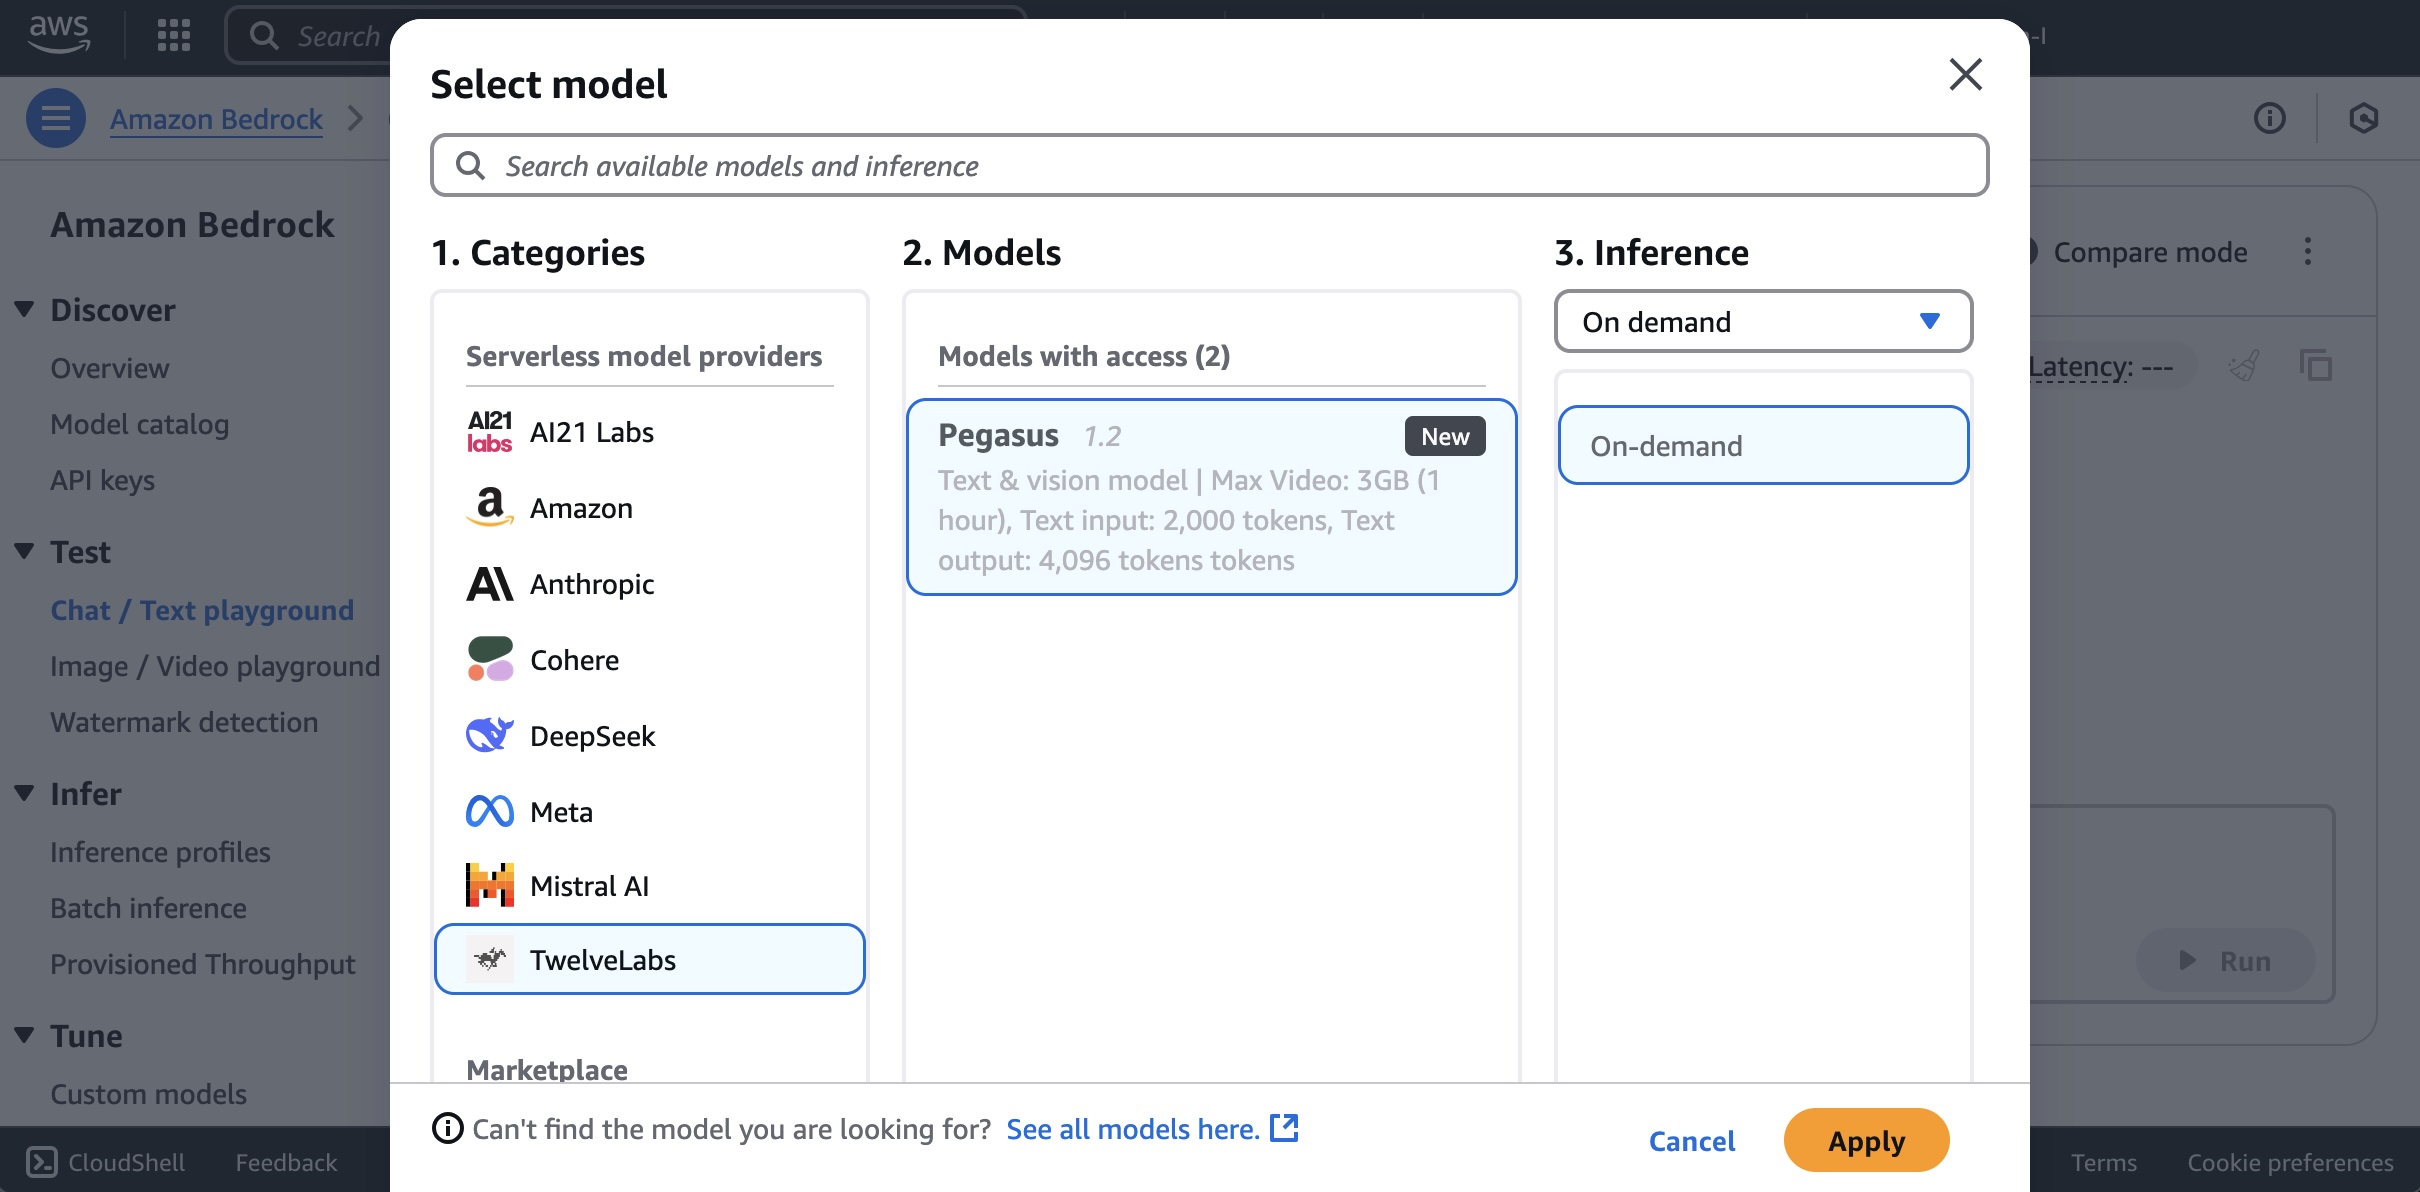
Next, to test the DeepSeek-V3.1 model in Amazon Bedrock, choose Chat/Text under Playgrounds in the left menu pane. Then choose Select model in the upper left, and select DeepSeek as the category and DeepSeek-V3.1 as the model. Then choose Apply.

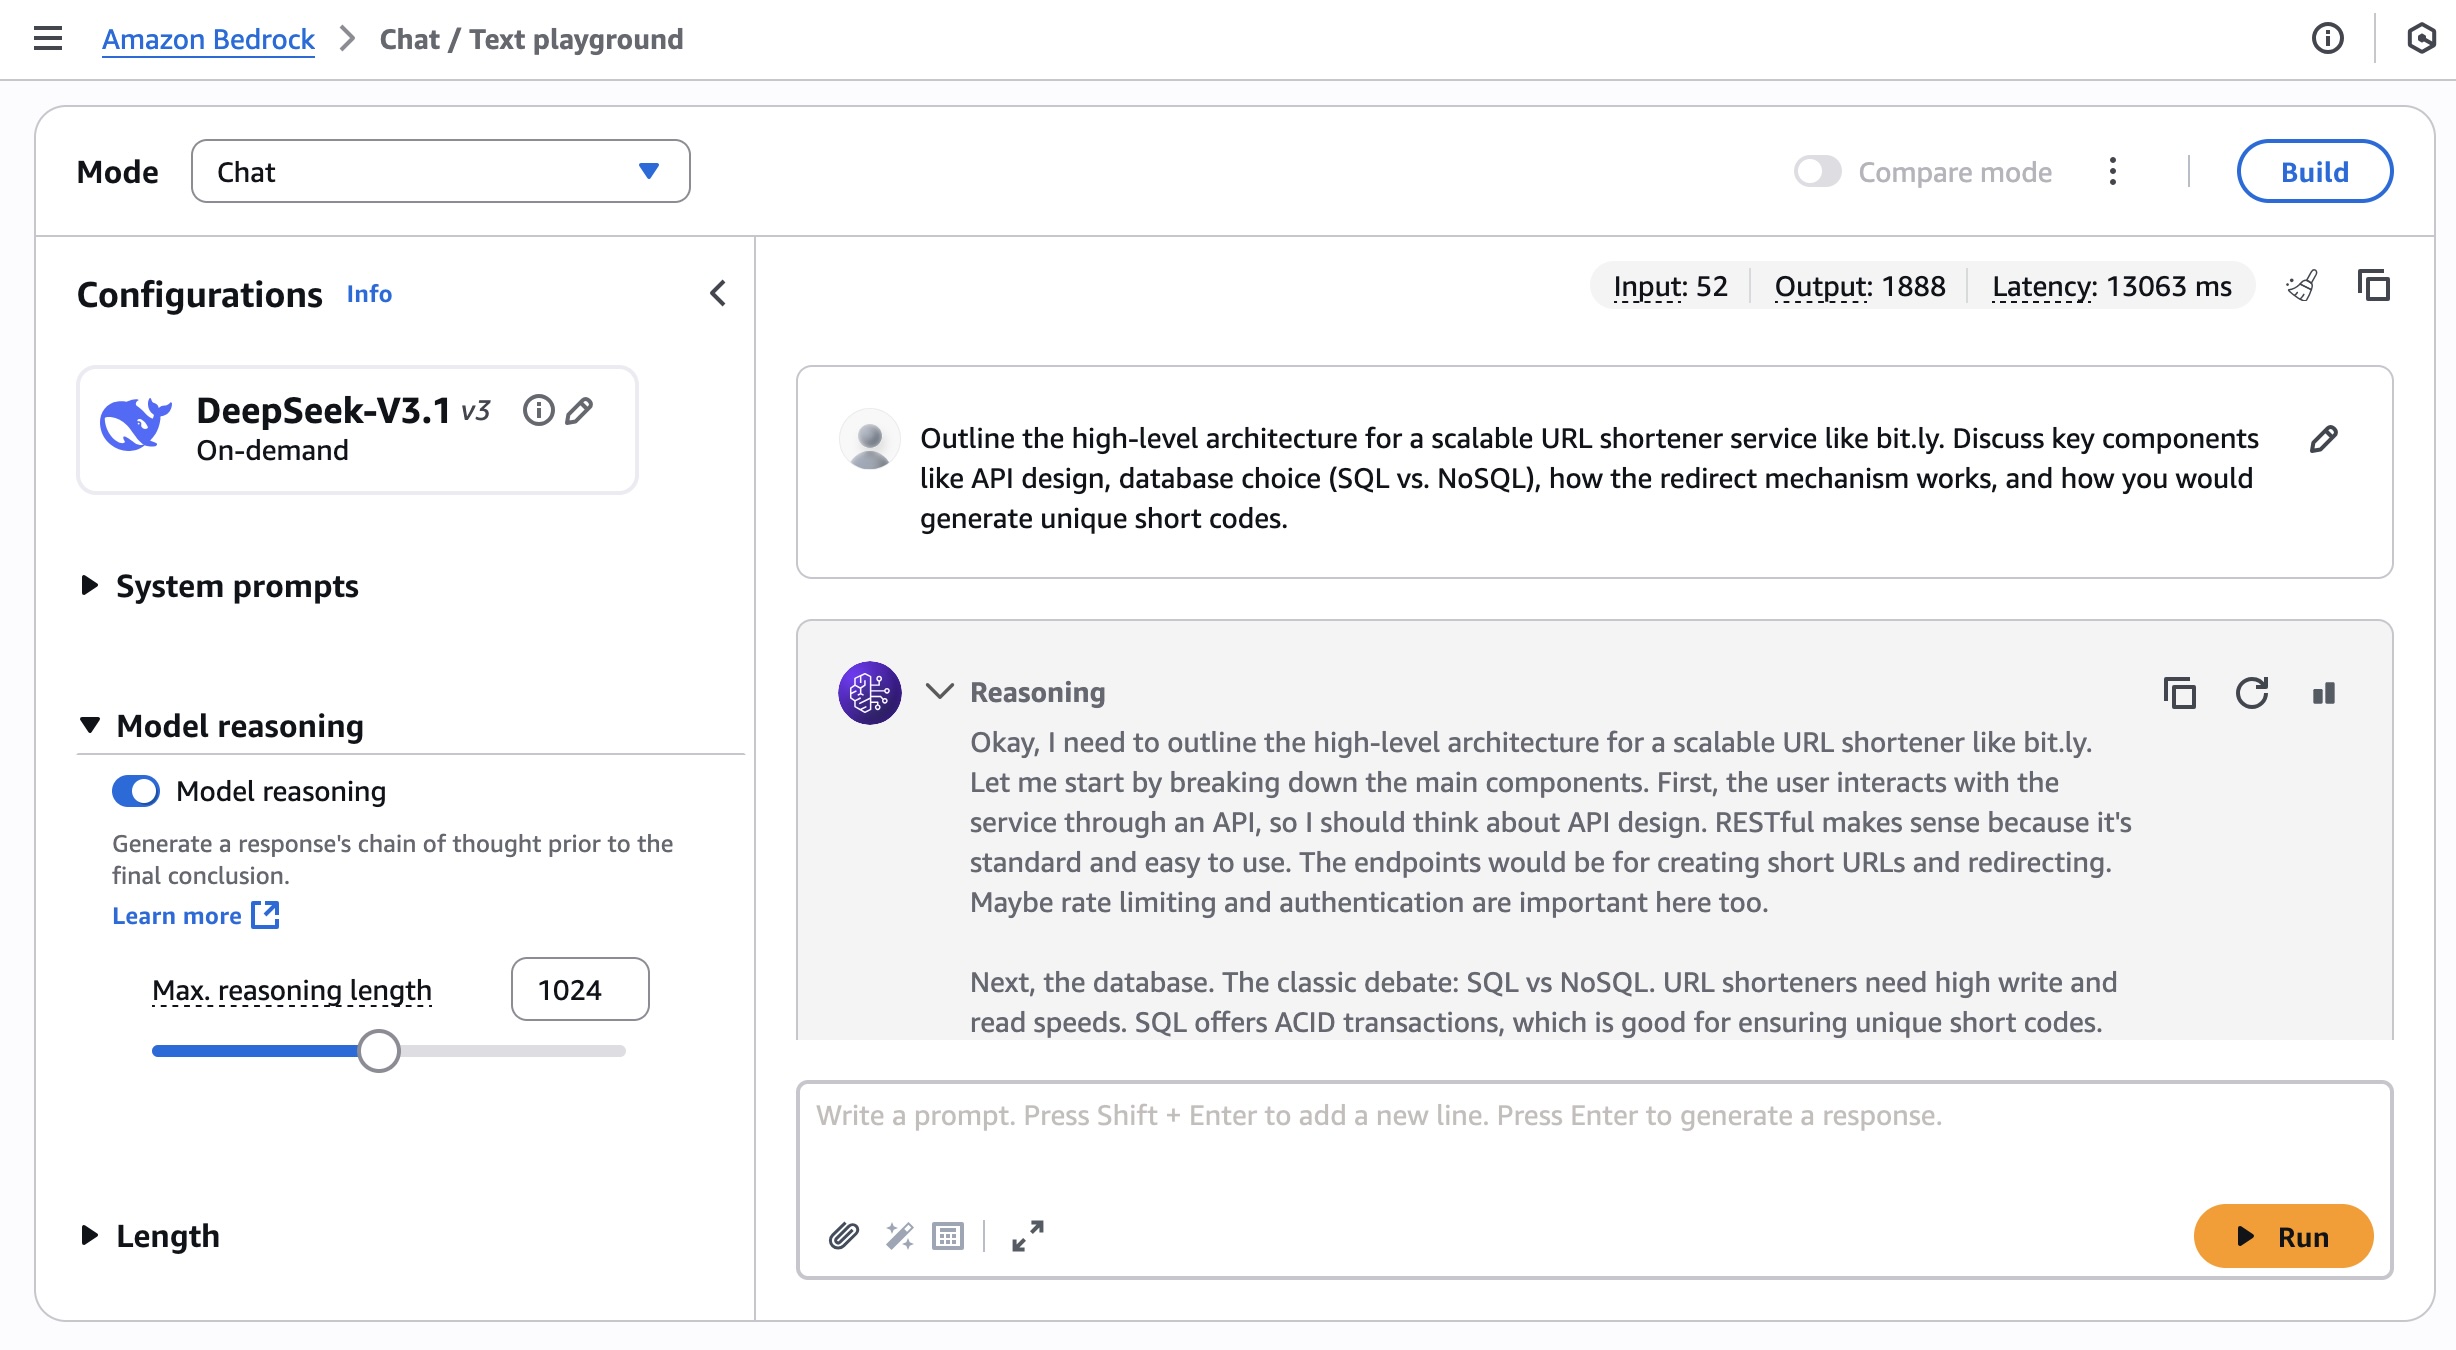
Using the selected DeepSeek-V3.1 model, I run the following prompt example about technical architecture decision.

Outline the high-level architecture for a scalable URL shortener service like bit.ly. Discuss key components like API design, database choice (SQL vs. NoSQL), how the redirect mechanism works, and how you would generate unique short codes.

You can turn the thinking on and off by toggling Model reasoning mode to generate a response’s chain of thought prior to the final conclusion.

You can also access the model using the AWS Command Line Interface (AWS CLI) and AWS SDK. This model supports both the InvokeModel and Converse API. You can check out a broad range of code examples for multiple use cases and a variety of programming languages.

To learn more, visit DeepSeek model inference parameters and responses in the AWS documentation.

Now available
DeepSeek-V3.1 is now available in the US West (Oregon), Asia Pacific (Tokyo), Asia Pacific (Mumbai), Europe (London), and Europe (Stockholm) AWS Regions. Check the full Region list for future updates. To learn more, check out the DeepSeek in Amazon Bedrock product page and the Amazon Bedrock pricing page.

Give the DeepSeek-V3.1 model a try in the Amazon Bedrock console today and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

Channy

OpenAI open weight models now available on AWS

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/openai-open-weight-models-now-available-on-aws/

AWS is committed to bringing you the most advanced foundation models (FMs) in the industry, continuously expanding our selection to include groundbreaking models from leading AI innovators so that you always have access to the latest advancements to drive your business forward.

Today, I am happy to announce the availability of two new OpenAI models with open weights in Amazon Bedrock and Amazon SageMaker JumpStart. OpenAI gpt-oss-120b and gpt-oss-20b models are designed for text generation and reasoning tasks, offering developers and organizations new options to build AI applications with complete control over their infrastructure and data.

These open weight models excel at coding, scientific analysis, and mathematical reasoning, with performance comparable to leading alternatives. Both models support a 128K context window and provide adjustable reasoning levels (low/medium/high) to match your specific use case requirements. The models support external tools to enhance their capabilities and can be used in an agentic workflow, for example, using a framework like Strands Agents.

With Amazon Bedrock and Amazon SageMaker JumpStart, AWS gives you the freedom to innovate with access to hundreds of FMs from leading AI companies, including OpenAI open weight models. With our comprehensive selection of models, you can match your AI workloads to the perfect model every time.

Through Amazon Bedrock, you can seamlessly experiment with different models, mix and match capabilities, and switch between providers without rewriting code—turning model choice into a strategic advantage that helps you continuously evolve your AI strategy as new innovations emerge. At launch, these new models are available in Bedrock via an OpenAI compatible endpoint. You can point the OpenAI SDK to this endpoint or use the Bedrock InvokeModel and Converse API.

With SageMaker JumpStart, you can quickly evaluate, compare, and customize models for your use case. You can then deploy the original or the customized model in production with the SageMaker AI console or using the SageMaker Python SDK.

Let’s see how these work in practice.

Getting started with OpenAI open weight models in Amazon Bedrock
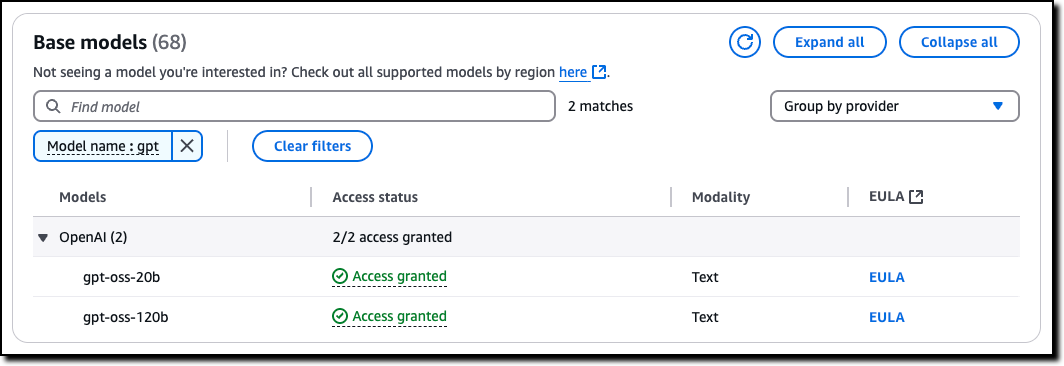
In the Amazon Bedrock console, I choose Model access from the Configure and learn section of the navigation pane. Then, I navigate to the two listed OpenAI models on this page and request access.

Console screenshot

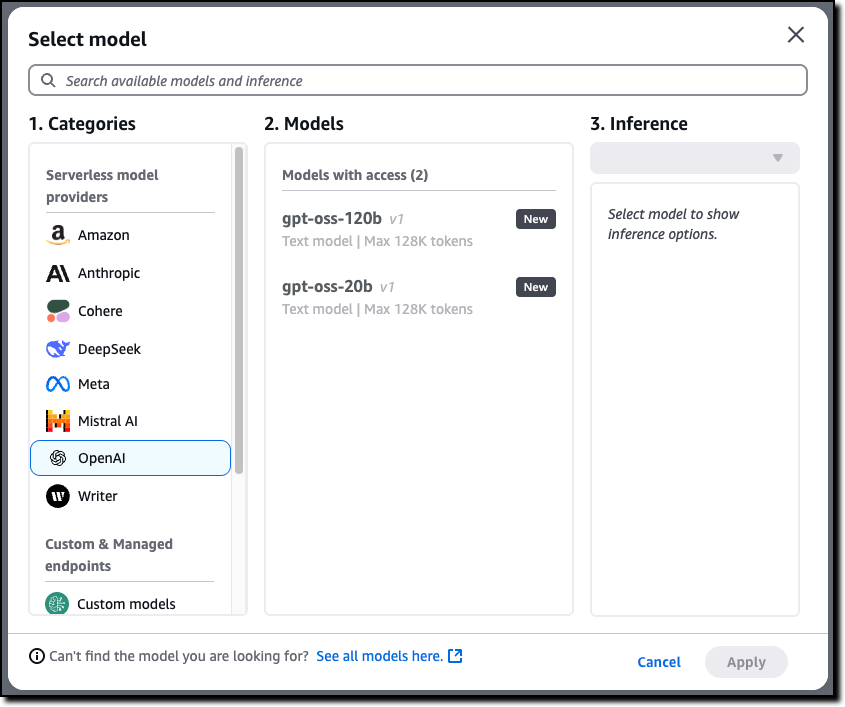
Now that I have access, I use the Chat/Test playground to test and evaluate the models. I select OpenAI as the category and then the gpt-oss-120b model.

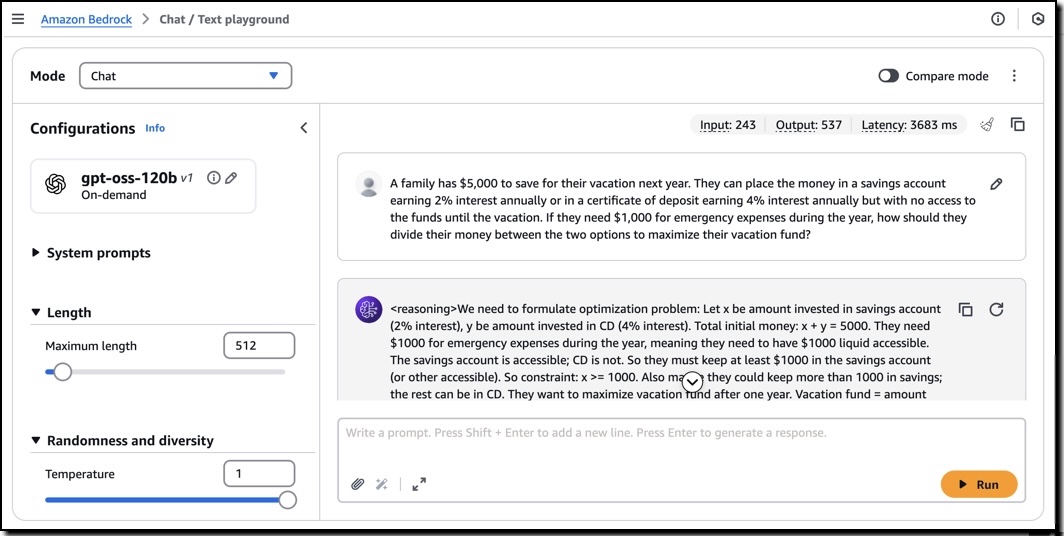
Console screenshot

Using this model, I run the following sample prompt:

A family has $5,000 to save for their vacation next year. They can place the money in a savings account earning 2% interest annually or in a certificate of deposit earning 4% interest annually but with no access to the funds until the vacation. If they need $1,000 for emergency expenses during the year, how should they divide their money between the two options to maximize their vacation fund?

This prompt generates an output that includes the chain of thought used to produce the result.

I can use these models with the OpenAI SDK by configuring the API endpoint (base URL) and using an Amazon Bedrock API key for authentication. For example, I set this environment variables to use the US West (Oregon) AWS Region endpoint (us-west-2) and my Amazon Bedrock API key:

export OPENAI_API_KEY="<my-bedrock-api-key>"
export OPENAI_BASE_URL="https://bedrock-runtime.us-west-2.amazonaws.com/openai/v1"

Now I invoke the model using the OpenAI Python SDK.

client = OpenAI()

response = client.chat.completion.create(
    messages=[{
        "role": "user",
        "content": "Hello, how are you?"
    }],
    model="openai.gpt-oss-120b-1:0",
    stream=True
)

for item in response:
    print(item)

To build an AI agent, I can choose any framework that supports the Amazon Bedrock API or the OpenAI API. For example, here’s the starting code for Strands Agents using the Amazon Bedrock API:

from strands import Agent
from strands.models import BedrockModel
from strands_tools import calculator

model = BedrockModel(
    model_id="openai.gpt-oss-120b-1:0"
)
agent = Agent(
    model=model,
    tools=[calculator]
)

agent("Tell me the square root of 42 ^ 3")

I save the code (app.py file), install the dependencies, and run the agent locally:

pip install strands-agents strands-agents-tools
python app.py

When I am satisfied with the agent, I can deploy in production using the capabilities offered by Amazon Bedrock AgentCore, including a fully managed serverless runtime and memory and identity management.

Getting started with OpenAI open weight models in Amazon SageMaker JumpStart
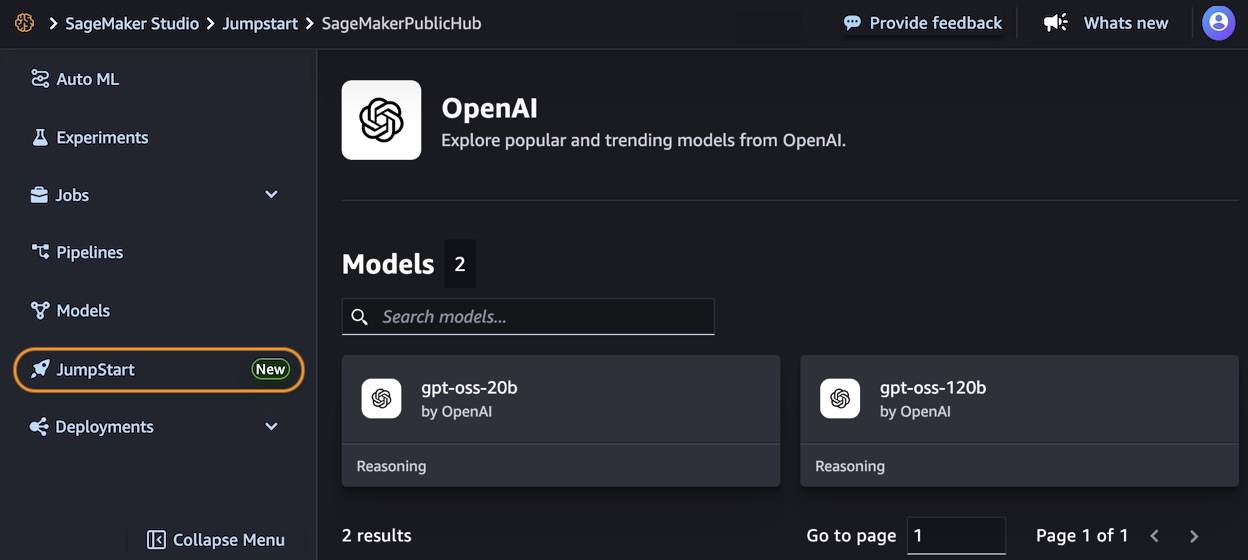
In the Amazon SageMaker AI console, you can use OpenAI open weight models in the SageMaker Studio. The first time I do this, I need to set up a SageMaker domain. There are options to set it up for a single user (simpler) or an organization. For these tests, I use a single user setup.

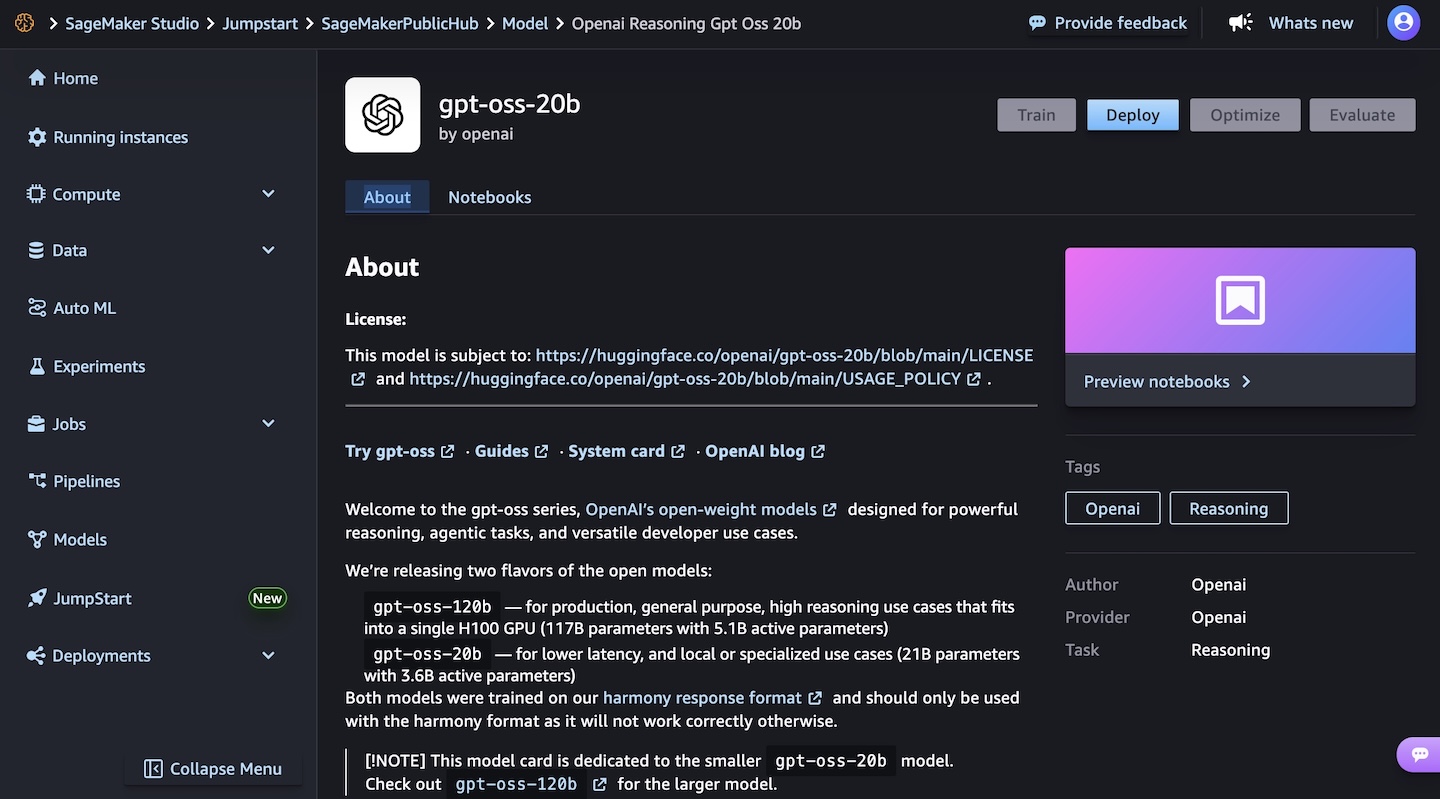
In the SageMaker JumpStart model view, I have access to a detailed description of the gpt-oss-120b or gpt-oss-20b model.

I choose the gpt-oss-20b model and then deploy the model. In the next steps, I select the instance type and the initial instance count. After a few minutes, the deployment creates an endpoint that I can then invoke in SageMaker Studio and using any AWS SDKs.

To learn more, visit GPT OSS models from OpenAI are now available on SageMaker JumpStart in the AWS Artificial Intelligence Blog.

Things to know
The new OpenAI open weight models are now available in Amazon Bedrock in the US West (Oregon) AWS Region, while Amazon SageMaker JumpStart supports these models in US East (Ohio, N. Virginia) and Asia Pacific (Mumbai, Tokyo).

Each model comes equipped with full chain-of-thought output capabilities, providing you with detailed visibility into the model’s reasoning process. This transparency is particularly valuable for applications requiring high levels of interpretability and validation. These models give you the freedom to modify, adapt, and customize them to your specific needs. This flexibility allows you to fine-tune the models for your unique use cases, integrate them into your existing workflows, and even build upon them to create new, specialized models tailored to your industry or application.

Security and safety are built into the core of these models, with comprehensive evaluation processes and safety measures in place. The models maintain compatibility with the standard GPT-4 tokenizer.

Both models can be used in your preferred environment, whether that’s through the serverless experience of Amazon Bedrock or the extensive machine learning (ML) development capabilities of SageMaker JumpStart. For information about the costs associated with using these models and services, visit the Amazon Bedrock pricing and Amazon SageMaker AI pricing pages.

To learn more, see the parameters for the models and the chat completions API in the Amazon Bedrock documentation.

Get started today with OpenAI open weight models on AWS in the Amazon Bedrock console or in Amazon SageMaker AI console.

Danilo

Introducing Amazon Bedrock AgentCore: Securely deploy and operate AI agents at any scale (preview)

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/introducing-amazon-bedrock-agentcore-securely-deploy-and-operate-ai-agents-at-any-scale/

In just a few years, foundation models (FMs) have evolved from being used directly to create content in response to a user’s prompt, to now powering AI agents, a new class of software applications that use FMs to reason, plan, act, learn, and adapt in pursuit of user-defined goals with limited human oversight. This new wave of agentic AI is enabled by the emergence of standardized protocols such as Model Context Protocol (MCP) and Agent2Agent (A2A) that simplify how agents connect with other tools and systems.

In fact, building AI agents that can reliably perform complex tasks has become increasingly accessible thanks to open source frameworks like CrewAILangGraph, and Strands Agents. However, moving from a promising proof-of-concept to a production-ready agent that can scale to thousands of users presents significant challenges.

Instead of being able to focus on the core features of the agent, developers and AI engineers have to spend months building foundational infrastructure for session management, identity controls, memory systems, and observability—at the same time supporting security and compliance.

Today, we’re excited to announce the preview of Amazon Bedrock AgentCore, a comprehensive set of enterprise-grade services that help developers quickly and securely deploy and operate AI agents at scale using any framework and model, hosted on Amazon Bedrock or elsewhere.

More specifically, we are introducing today:

AgentCore Runtime – Provides sandboxed low-latency serverless environments with session isolation, supporting any agent framework including popular open source frameworks, tools, and models, and handling multimodal workloads and long-running agents.

AgentCore Memory – Manages session and long-term memory, providing relevant context to models while helping agents learn from past interactions.

AgentCore Observability – Offers step-by-step visualization of agent execution with metadata tagging, custom scoring, trajectory inspection, and troubleshooting/debugging filters.

AgentCore Identity – Enables AI agents to securely access AWS services and third-party tools and services such as GitHub, Salesforce, and Slack, either on behalf of users or by themselves with pre-authorized user consent.

AgentCore Gateway – Transforms existing APIs and AWS Lambda functions into agent-ready tools, offering unified access across protocols, including MCP, and runtime discovery.

AgentCore Browser – Provides managed web browser instances to scale your agents’ web automation workflows.

AgentCore Code Interpreter – Offers an isolated environment to run the code your agents generate.

These services can be used individually and are optimized to work together so developers don’t need to spend time piecing together components. AgentCore can work with open source or custom AI agent frameworks, giving teams the flexibility to maintain their preferred tools while gaining enterprise capabilities. To integrate these services into their existing code, developers can use the AgentCore SDK.

You can now discover, buy, and run pre-built agents and agent tools from AWS Marketplace with AgentCore Runtime. With just a few lines of code, your agents can securely connect to API-based agents and tools from AWS Marketplace with AgentCore Gateway to help you run complex workflows while maintaining compliance and control.

AgentCore eliminates tedious infrastructure work and operational complexity so development teams can bring groundbreaking agentic solutions to market faster.

Let’s see how this works in practice. I’ll share more info on the services as we use them.

Deploying a production-ready customer support assistant with Amazon Bedrock AgentCore (Preview)
When customers reach out with an email, it takes time to provide a reply. Customer support needs to check the validity of the email, find who the actual customer is in the customer relationship management (CRM) system, check their orders, and use product-specific knowledge bases to find the information required to prepare an answer.

An AI agent can simplify that by connecting to the internal systems, retrieve contextual information using a semantic data source, and draft a reply for the support team. For this use case, I built a simple prototype using Strands Agents. For simplicity and to validate the scenario, the internal tools are simulated using Python functions.

When I talk to developers, they tell me that similar prototypes, covering different use cases, are being built in many companies. When these prototypes are demonstrated to the company leadership and receive confirmation to proceed, the development team has to define how to go in production and satisfy the usual requirements for security, performance, availability, and scalability. This is where AgentCore can help.

Step 1 – Deploying to the cloud with AgentCore Runtime

AgentCore Runtime is a new service to securely deploy, run, and scale AI agents, providing isolation so that each user session runs in its own protected environment to help prevent data leakage—a critical requirement for applications handling sensitive data.

To match different security postures, agents can use different network configurations:

Sandbox – To only communicate with allowlisted AWS services.

Public – To run with managed internet access.

VPC-only (coming soon) – This option will allow to access resources hosted in a customer’s VPC or connected via AWS PrivateLink endpoints.

To deploy the agent to the cloud and get a secure, serverless endpoint with AgentCore Runtime, I add to the prototype a few lines of code using the AgentCore SDK to:

  • Import the AgentCore SDK.
  • Create the AgentCore app.
  • Specify which function is the entry point to invoke the agent.

Using a different or custom agent framework is a matter of replacing the agent invocation inside the entry point function.

Here’s the code of the prototype. The three lines I added to use AgentCore Runtime are the ones preceded by a comment.

from strands import Agent, tool
from strands_tools import calculator, current_time

# Import the AgentCore SDK
from bedrock_agentcore.runtime import BedrockAgentCoreApp

WELCOME_MESSAGE = """
Welcome to the Customer Support Assistant! How can I help you today?
"""

SYSTEM_PROMPT = """
You are an helpful customer support assistant.
When provided with a customer email, gather all necessary info and prepare the response email.
When asked about an order, look for it and tell the full description and date of the order to the customer.
Don't mention the customer ID in your reply.
"""

@tool
def get_customer_id(email_address: str):
    if email_address == "[email protected]":
        return { "customer_id": 123 }
    else:
        return { "message": "customer not found" }

@tool
def get_orders(customer_id: int):
    if customer_id == 123:
        return [{
            "order_id": 1234,
            "items": [ "smartphone", "smartphone USB-C charger", "smartphone black cover"],
            "date": "20250607"
        }]
    else:
        return { "message": "no order found" }

@tool
def get_knowledge_base_info(topic: str):
    kb_info = []
    if "smartphone" in topic:
        if "cover" in topic:
            kb_info.append("To put on the cover, insert the bottom first, then push from the back up to the top.")
            kb_info.append("To remove the cover, push the top and bottom of the cover at the same time.")
        if "charger" in topic:
            kb_info.append("Input: 100-240V AC, 50/60Hz")
            kb_info.append("Includes US/UK/EU plug adapters")
    if len(kb_info) > 0:
        return kb_info
    else:
        return { "message": "no info found" }

# Create an AgentCore app
app = BedrockAgentCoreApp()

agent = Agent(
    system_prompt=SYSTEM_PROMPT,
    tools=[calculator, current_time, get_customer_id, get_orders, get_knowledge_base_info]
)

# Specify the entrypoint function invoking the agent
@app.entrypoint
def invoke(payload, context: RequestContext):
    """Handler for agent invocation"""
    user_message = payload.get(
        "prompt", "No prompt found in input, please guide customer to create a json payload with prompt key"
    )
    result = agent(user_message)
    return {"result": result.message}

if __name__ == "__main__":
    app.run()

I install the AgentCore SDK and the starter toolkit in the Python virtual environment:

pip install bedrock-agentcore bedrock-agentcore-starter-toolkit

After I activate the virtual environment, I have access to the AgentCore command line interface (CLI) provided by the starter toolkit.

First, I use agentcore configure --entrypoint my_agent.py -er <IAM_ROLE_ARN> to configure the agent, passing the AWS Identity and Access Management (IAM) role that the agent will assume. In this case, the agent needs access to Amazon Bedrock to invoke the model. The role can give access to other AWS resources used by an agent, such as an Amazon Simple Storage Service (Amazon S3) bucket or a Amazon DynamoDB table.

I launch the agent locally with agentcore launch --local. When running locally, I can interact with the agent using agentcore invoke --local <PAYLOAD>. The payload is passed to the entry point function. Note that the JSON syntax of the invocations is defined in the entry point function. In this case, I look for prompt in the JSON payload, but can use a different syntax depending on your use case.

When I am satisfied by local testing, I use agentcore launch to deploy to the cloud.

After the deployment is succesful and an endpoint has been created, I check the status of the endpoint with agentcore status and invoke the endpoint with agentcore invoke <PAYLOAD>. For example, I pass a customer support request in the invocation:

agentcore invoke '{"prompt": "From: [email protected] – Hi, I bought a smartphone from your store. I am traveling to Europe next week, will I be able to use the charger? Also, I struggle to remove the cover. Thanks, Danilo"}'

Step 2 – Enabling memory for context

After an agent has been deployed in the AgentCore Runtime, the context needs to be persisted to be available for a new invocation. I add AgentCore Memory to maintain session context using its short-term memory capabilities.

First, I create a memory client and the memory store for the conversations:

from bedrock_agentcore.memory import MemoryClient

memory_client = MemoryClient(region_name="us-east-1")

memory = memory_client.create_memory_and_wait(
    name="CustomerSupport", 
    description="Customer support conversations"
)

I can now use create_event to stores agent interactions into short-term memory:

memory_client.create_event(
    memory_id=memory.get("id"), # Identifies the memory store
    actor_id="user-123",        # Identifies the user
    session_id="session-456",   # Identifies the session
    messages=[
        ("Hi, ...", "USER"),
        ("I'm sorry to hear that...", "ASSISTANT"),
        ("get_orders(customer_id='123')", "TOOL"),
        . . .
    ]
)

I can load the most recent turns of a conversations from short-term memory using list_events:

conversations = memory_client.list_events(
    memory_id=memory.get("id"), # Identifies the memory store
    actor_id="user-123",        # Identifies the user 
    session_id="session-456",   # Identifies the session
    max_results=5               # Number of most recent turns to retrieve
)

With this capability, the agent can maintain context during long sessions. But when a users come back with a new session, the conversation starts blank. Using long-term memory, the agent can personalize user experiences by retaining insights across multiple interactions.

To extract memories from a conversation, I can use built-in AgentCore Memory policies for user preferences, summarization, and semantic memory (to capture facts) or create custom policies for specialized needs. Data is stored encrypted using a namespace-based storage for data segmentation.

I change the previous code creating the memory store to include long-term capabilities by passing a semantic memory strategy. Note that an existing memory store can be updated to add strategies. In that case, the new strategies are applied to newer events.

memory = memory_client.create_memory_and_wait(
    name="CustomerSupport", 
    description="Customer support conversations",
    strategies=[{
        "semanticMemoryStrategy": {
            "name": "semanticFacts",
            "namespaces": ["/facts/{actorId}"]
        }
    }]
)

After long-term memory has been configured for a memory store, calling create_event will automatically apply those strategies to extract information from the conversations. I can then retrieve memories extracted from the conversation using a semantic query:

memories = memory_client.retrieve_memories(
    memory_id=memory.get("id"),
    namespace="/facts/user-123",
    query="smartphone model"
)

In this way, I can quickly improve the user experience so that the agent remembers customer preferences and facts that are outside of the scope of the CRM and use this information to improve the replies.

Step 3 – Adding identity and access controls

Without proper identity controls, access from the agent to internal tools always uses the same access level. To follow security requirements, I integrate AgentCore Identity so that the agent can use access controls scoped to the user’s or agent’s identity context.

I set up an identity client and create a workload identity, a unique identifier that represents the agent within the AgentCore Identity system:

from bedrock_agentcore.services.identity import IdentityClient

identity_client = IdentityClient("us-east-1")
workload_identity = identity_client.create_workload_identity(name="my-agent")

Then, I configure the credential providers, for example:

google_provider = identity_client.create_oauth2_credential_provider(
    {
        "name": "google-workspace",
        "credentialProviderVendor": "GoogleOauth2",
        "oauth2ProviderConfigInput": {
            "googleOauth2ProviderConfig": {
                "clientId": "your-google-client-id",
                "clientSecret": "your-google-client-secret",
            }
        },
    }
)

perplexity_provider = identity_client.create_api_key_credential_provider(
    {
        "name": "perplexity-ai",
        "apiKey": "perplexity-api-key"
    }
)

I can then add the @requires_access_token Python decorator (passing the provider name, the scope, and so on) to the functions that need an access token to perform their activities.

Using this approach, the agent can verify the identity through the company’s existing identity infrastructure, operate as a distinct, authenticated identity, act with scoped permissions and integrate across multiple identity providers (such as Amazon Cognito, Okta, or Microsoft Entra ID) and service boundaries including AWS and third-party tools and services (such as Slack, GitHub, and Salesforce).

To offer robust and secure access controls while streamlining end-user and agent builder experiences, AgentCore Identity implements a secure token vault that stores users’ tokens and allows agents to retrieve them securely.

For OAuth 2.0 compatible tools and services, when a user first grants consent for an agent to act on their behalf, AgentCore Identity collects and stores the user’s tokens issued by the tool in its vault, along with securely storing the agent’s OAuth client credentials. Agents, operating with their own distinct identity and when invoked by the user, can then access these tokens as needed, reducing the need for frequent user consent.

When the user token expires, AgentCore Identity triggers a new authorization prompt to the user for the agent to obtain updated user tokens. For tools that use API keys, AgentCore Identity also stores these keys securely and gives agents controlled access to retrieve them when needed. This secure storage streamlines the user experience while maintaining robust access controls, enabling agents to operate effectively across various tools and services.

Step 4 – Expanding agent capabilities with AgentCore Gateway

Until now, all internal tools are simulated in the code. Many agent frameworks, including Strands Agents, natively support MCP to connect to remote tools. To have access to internal systems (such as CRM and order management) via an MCP interface, I use AgentCore Gateway.

With AgentCore Gateway, the agent can access AWS services using Smithy models, Lambda functions, and internal APIs and third-party providers using OpenAPI specifications. It employs a dual authentication model to have secure access control for both incoming requests and outbound connections to target resources. Lambda functions can be used to integrate external systems, particularly applications that lack standard APIs or require multiple steps to retrieve information.

AgentCore Gateway facilitates cross-cutting features that most customers would otherwise need to build themselves, including authentication, authorization, throttling, custom request/response transformation (to match underlying API formats), multitenancy, and tool selection.

The tool selection feature helps find the most relevant tools for a specific agent’s task. AgentCore Gateway brings a uniform MCP interface across all these tools, using AgentCore Identity to provide an OAuth interface for tools that do not support OAuth out of the box like AWS services.

Step 5 – Adding capabilities with AgentCore Code Interpreter and Browser tools

To answer to customer requests, the customer support agent needs to perform calculations. To simplify that, I use the AgentCode SDK to add access to the AgentCore Code Interpreter.

Similarly, some of the integrations required by the agent don’t implement a programmatic API but need to be accessed through a web interface. I give access to the AgentCore Browser to let the agent navigate those web sites autonomously.

Step 6 – Gaining visibility with observability

Now that the agent is in production, I need visibility into its activities and performance. AgentCore provides enhanced observability to help developers effectively debug, audit, and monitor their agent performance in production. It comes with built-in dashboards to track essential operational metrics such as session count, latency, duration, token usage, error rates, and component-level latency and error breakdowns. AgentCore also gives visibility into an agent’s behavior by capturing and visualizing both the end-to-end traces, as well as “spans” that capture each step of the agent workflow including tool invocations, memory

The built-in dashboards offered by this service help reveal performance bottlenecks and identify why certain interactions might fail, enabling continuous improvement and reducing the mean time to detect (MTTD) and mean time to repair (MTTR) in case of issues.

AgentCore supports OpenTelemetry to help integrate agent telemetry data with existing observability platforms, including Amazon CloudWatch, Datadog, LangSmith, and Langfuse.

Step 7 – Conclusion

Through this journey, we transformed a local prototype into a production-ready system. Using AgentCore modular approach, we implemented enterprise requirements incrementally—from basic deployment to sophisticated memory, identity management, and tool integration—all while maintaining the existing agent code.

Things to know
Amazon Bedrock AgentCore is available in preview in US East (N. Virginia), US West (Oregon), Asia Pacific (Sydney), and Europe (Frankfurt). You can start using AgentCore services through the AWS Management Console , the AWS Command Line Interface (AWS CLI), the AWS SDKs, or via the AgentCore SDK.

You can try AgentCore services at no charge until September 16, 2025. Standard AWS pricing applies to any additional AWS Services used as part of using AgentCore (for example, CloudWatch pricing will apply for AgentCore Observability). Starting September 17, 2025, AWS will bill you for AgentCore service usage based on this page.

Whether you’re building customer support agents, workflow automation, or innovative AI-powered experiences, AgentCore provides the foundation you need to move from prototype to production with confidence.

To learn more and start deploying production-ready agents, visit the AgentCore documentation. For code examples and integration guides, check out the AgentCore samples GitHub repo.

Join the AgentCore Preview Discord server to provide feedback and discuss use cases. We’d like to hear from you!

Danilo

TwelveLabs video understanding models are now available in Amazon Bedrock

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/twelvelabs-video-understanding-models-are-now-available-in-amazon-bedrock/

Earlier this year, we preannounced that TwelveLabs video understanding models were coming to Amazon Bedrock. Today, we’re announcing the models are now available for searching through videos, classifying scenes, summarizing, and extracting insights with precision and reliability.

TwelveLabs has introduced Marengo, a video embedding model proficient at performing tasks such as search and classification, and Pegasus, a video language model that can generate text based on video data. These models are trained on Amazon SageMaker HyperPod to deliver groundbreaking video analysis that provides text summaries, metadata generation, and creative optimization.

With the TwelveLabs models in Amazon Bedrock, you can find specific moments using natural language video search capabilities like “show me the first touchdown of the game” or “find the scene where the main characters first meet” and instantly jump to those exact moments. You can also build applications to understand video content by generating descriptive text such as titles, topics, hashtags, summaries, chapters, or highlights for discovering insights and connections without requiring predefined labels or categories.

For example, you can find recurring themes in customer feedback or spot product usage patterns that weren’t obvious before. Whether you have hundreds or thousands of hours of video content, you can now transform that entire library into a searchable knowledge resource while maintaining enterprise-grade security and performance.

Let’s take a look at the Marengo and Pegasus videos that TwelveLabs has published.

You can transform video workflows with these models across industries. Media producers and editors can instantly locate specific scenes or dialogue, which means you can focus on storytelling rather than sifting through hours of footage. Marketing teams are streamlining their advertising workflows by quickly personalizing content to resonate with various audiences, while security teams are using the technology to proactively identify potential risks by spotting patterns across multiple video feeds.

Getting started with TwelveLabs models in Amazon Bedrock
Before getting started, if you’re new to using TwelveLabs models, go to the Amazon Bedrock console and choose Model access in the bottom left navigation pane. To access the latest TwelveLabs models, request access for Marengo Embed 2.7 and Pegasus 1.2 in TwelveLabs.

To use TwelveLabs models in Amazon Bedrock, choose Chat/Text Playground under Test in the left navigation pane. Choose Select model, select TwelveLabs as the category and Pegasus as the model, and then choose Apply.

For searching or generating text from your video, you should upload your video to an Amazon Simple Storage Service (Amazon S3) bucket or input Base64-formatted video string.

I will use a sample video generated with Amazon Nova Reel with a prompt: “A cute raccoon playing guitar underwater.”

Enter the S3 URI of your uploaded video and the S3 Bucket Owner, and then run your prompt: “Tell me about the video by timeline”.

You can get following model response:

The video opens with an underwater scene featuring a sandy seabed and swaying seaweed, creating a serene atmosphere. At around 5 seconds, a raccoon appears, swimming towards the camera with a curious expression. By 10 seconds, the raccoon is seen swimming near the seabed. The focus then shifts to a group of koi fish swimming gracefully near the seabed from 11 to 13 seconds.

At 14 seconds, the scene transitions to an ukulele resting on the seabed, with the camera zooming in to highlight its details. The raccoon reappears at 20 seconds, swimming among the koi fish, and by 23 seconds, it begins to play the ukulele. The raccoon continues to play the ukulele from 29 to 41 seconds, with the koi fish swimming around it, adding a lively and colorful touch to the underwater setting.

From 42 to 49 seconds, the raccoon is shown playing the ukulele with the koi fish swimming around it. The video concludes with a screen displaying "Video generated with Amazon Novo Reel 1.1" and "Available in Amazon Bedrock" from 50 to 54 seconds, followed by the AWS logo from 55 to 57 seconds.

The TwelveLabs models can be easily integrated into your applications using the Amazon Bedrock Converse API, which provides a unified interface for conversational AI interactions.

Here’s an example of how to use the AWS SDK for Python (Boto3) with the TwelveLabs Pegasus model:

import boto3
import json
import os

AWS_REGION = "us-east-1"
MODEL_ID = "twelvelabs.pegasus-1-2-v1:0"
VIDEO_PATH = "sample.mp4"

def read_file(file_path: str) -> bytes:
    """Read a file in binary mode."""
    try:
        with open(file_path, 'rb') as file:
            return file.read()
    except Exception as e:
        raise Exception(f"Error reading file {file_path}: {str(e)}")

bedrock_runtime = boto3.client(
    service_name="bedrock-runtime",
    region_name=AWS_REGION
)

request_body = {
    "messages": [
        {
            "role": "user",
            "content": [
                {
                    "inputPrompt": "tell me about the video",
                    "mediaSource: {
                        "base64String": read_file(VIDEO_PATH)
                    }
                },
            ],
        }
    ]
}

response = bedrock_runtime.converse(
    modelId=MODEL_ID,
    messages=request_body["messages"]
)

print(response["output"]["message"]["content"][-1]["text"])

The TwelveLabs Marengo Embed 2.7 model generates vector embeddings from video, text, audio, or image inputs. These embeddings can be used for similarity search, clustering, and other machine learning (ML) tasks. The model supports asynchronous inference through the Bedrock AsyncInvokeModel API.

For video source, you can request JSON format for the TwelveLabs Marengo Embed 2.7 model using the AsyncInvokeModel API.

{
    "modelId": "twelvelabs.marengo-embed-2.7",
    "modelInput": {
        "inputType": "video",
        "mediaSource": {
            "s3Location": {
                "uri": "s3://your-video-object-s3-path",
                "bucketOwner": "your-video-object-s3-bucket-owner-account"
            }
        }
    },
    "outputDataConfig": {
        "s3OutputDataConfig": {
            "s3Uri": "s3://your-bucket-name"
        }
    }
}

You can get a response delivered to the specified S3 location.

{
    "embedding": [0.345, -0.678, 0.901, ...],
    "embeddingOption": "visual-text",
    "startSec": 0.0,
    "endSec": 5.0
}

To help you get started, check out a broad range of code examples for multiple use cases and a variety of programming languages. To learn more, visit TwelveLabs Pegasus 1.2 and TwelveLabs Marengo Embed 2.7 in the AWS Documentation.

Now available
TwelveLabs models are generally available today in Amazon Bedrock: the Marengo model in the US East (N. Virginia), Europe (Ireland), and Asia Pacific (Seoul) Region, and the Pegasus model in US West (Oregon), and Europe (Ireland) Region accessible with cross-Region inference from US and Europe Regions. Check the full Region list for future updates. To learn more, visit the TwelveLabs in Amazon Bedrock product page and the Amazon Bedrock pricing page.

Give TwelveLabs models a try on the Amazon Bedrock console today, and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

Channy

Amazon FSx for Lustre launches new storage class with the lowest-cost and only fully elastic Lustre file storage

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/amazon-fsx-for-lustre-adds-new-storage-class-with-the-lowest-cost-and-only-fully-elastic-lustre-file-storage/

Seismic imaging is a geophysical technique used to create detailed pictures of the Earth’s subsurface structure. It works by generating seismic waves that travel into the ground, reflect off various rock layers and structures, and return to the surface where they’re detected by sensitive instruments known as geophones or hydrophones. The huge volumes of acquired data often reach petabytes for a single survey and this presents significant storage, processing, and management challenges for researchers and energy companies.

Customers who run these seismic imaging workloads or other high performance computing (HPC) workloads, such as weather forecasting, advanced driver-assistance system (ADAS) training, or genomics analysis, already store the huge volumes of data on either hard disk drive (HDD)-based or a combination of HDD and solid state drive (SSD) file storage on premises. However, as these on premises datasets and workloads scale, customers find it increasingly challenging and expensive due to the need to make upfront capital investments to keep up with performance needs of their workloads and avoid running out of storage capacity.

Today, we’re announcing the general availability of the Amazon FSx for Lustre Intelligent-Tiering, a new storage class that delivers virtually unlimited scalability, the only fully elastic Lustre file storage, and the lowest cost Lustre file storage in the cloud. With a starting price of less than $0.005 per GB-month, FSx for Lustre Intelligent-Tiering offers the lowest cost high-performance file storage in the cloud, reducing storage costs for infrequently accessed data by up to 96 percent compared to other managed Lustre options. Elasticity means you no longer need to provision storage capacity upfront because your file system will grow and shrink as you add or delete data, and you pay only for the amount of data you store.

FSx for Lustre Intelligent-Tiering automatically optimizes costs by tiering cold data to the applicable lower-cost storage tier based on access patterns and includes an optional SSD read cache to improve performance for your most latency sensitive workloads. Intelligent-Tiering delivers high performance whether you’re starting with gigabytes of experimental data or working with large petabyte-scale datasets for your most demanding artificial intelligence/machine learning (AI/ML) and HPC workloads. With the flexibility to adjust your file system’s performance independent of storage, Intelligent-Tiering delivers up to 34 percent better price performance than on premises HDD file systems. The Intelligent-Tiering storage class is optimized for HDD-based or mixed HDD/SSD workloads that have a combination of hot and cold data. You can migrate and run such workloads to FSx for Lustre Intelligent-Tiering without application changes, eliminating storage capacity planning and management, while paying only for the resources that you use.

Prior to this launch, customers used the FSx for Lustre SSD storage class to accelerate ML and HPC workloads that need all-SSD performance and consistent low-latency access to all data. However, many workloads have a combination of hot and cold data and they don’t need all-SSD storage for colder portions of the data. FSx for Lustre is increasingly used in AI/ML workloads to increase graphics processing unit (GPU) utilization, and now it’s even more cost optimized to be one of the options for these workloads.

FSx for Lustre Intelligent-Tiering
Your data moves between three storage tiers (Frequent Access, Infrequent Access, and Archive) with no effort on your part, so you get automatic cost savings with no upfront costs or commitments. The tiering works as follows:

Frequent Access – Data that has been accessed within the last 30 days is stored in this tier.

Infrequent Access – Data that hasn’t been accessed for 30 – 90 days is stored in this tier, at a 44 percent cost reduction from Frequent Access.

Archive – Data that hasn’t been accessed for 90 or more days is stored in this tier, at a 65 percent cost reduction compared to Infrequent Access.

Regardless of the storage tier, your data is stored across multiple AWS Availability Zones for redundancy and availability, compared to typical on-premises implementations, which are usually confined within a single physical location. Additionally, your data can be retrieved instantly in milliseconds.

Creating a file system
I can create a file system using the AWS Management Console, AWS Command Line Interface (AWS CLI), API, or AWS CloudFormation. On the console, I choose Create file system to get started.


I select Amazon FSx for Lustre and choose Next.


Now, it’s time to enter the rest of the information to create the file system. I enter a name (veliswa_fsxINT_1) for my file system, and for deployment and storage class, I select Persistent, Intelligent-Tiering. I choose the desired Throughput capacity and the Metadata IOPS. The SSD read cache will be automatically configured by FSx for Lustre based on the specified throughput capacity. I leave the rest as the default, choose Next, and review my choices to create my file system.

With Amazon FSx for Lustre Intelligent-Tiering, you have the flexibility to provision the necessary performance for your workloads without having to provision any underlying storage capacity upfront.


I wanted to know which values were editable after creation, so I paid closer attention before finalizing the creation of the file system. I noted that Throughput capacity, Metadata IOPS, Security groups, SSD read cache, and a few others were editable later. After I start running the ML jobs, it might be necessary to increase the throughput capacity based on the volumes of data I’ll be processing, so this information is important to me.

The file system is now available. Considering that I’ll be running HPC workloads, I anticipate that I’ll be processing high volumes of data later, so I’ll increase the throughput capacity to 24 GB/s. After all, I only pay for the resources I use.


The SSD read cache is scaled automatically as your performance needs increase. You can adjust the cache size any time independently in user-provisioned mode or disable the read cache if you don’t need low-latency access.


Good to know

  • FSx for Lustre Intelligent-Tiering is designed to deliver up to multiple terabytes per second of total throughput.
  • FSx for Lustre with Elastic Fabric Adapter (EFA)/GPU Direct Storage (GDS) support provides up to 12x (up to 1200 Gbps) higher per-client throughput compared to the previous FSx for Lustre systems.
  • It can deliver up to tens of millions of IOPS for writes and cached reads. Data in the SSD read cache has submillisecond time-to-first-byte latencies, and all other data has time-to-first-byte latencies in the range of tens of milliseconds.

Now available
Here are a couple of things to keep in mind:

FSx Intelligent-Tiering storage class is available in the new FSx for Lustre file systems in the US East (N. Virginia, Ohio), US West (N. California, Oregon), Canada (Central), Europe (Frankfurt, Ireland, London, Stockholm), and Asia Pacific (Hong Kong, Mumbai, Seoul, Singapore, Sydney, Tokyo) AWS Regions.

You pay for data and metadata you store on your file system (GB/months). When you write data or when you read data that is not in the SSD read cache, you pay per operation. You pay for the total throughput capacity (in MBps/month), metadata IOPS (IOPS/month), and SSD read cache size for data and metadata (GB/month) you provision on your file system. To learn more, visit the Amazon FSx for Lustre Pricing page. To learn more about Amazon FSx for Lustre including this feature, visit the Amazon FSx for Lustre page.

Give Amazon FSx for Lustre Intelligent-Tiering a try in the Amazon FSx console today and send feedback to AWS re:Post for Amazon FSx for Lustre or through your usual AWS Support contacts.

Veliswa.


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Introducing Claude 4 in Amazon Bedrock, the most powerful models for coding from Anthropic

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/claude-opus-4-anthropics-most-powerful-model-for-coding-is-now-in-amazon-bedrock/

Anthropic launched the next generation of Claude models today—Opus 4 and Sonnet 4—designed for coding, advanced reasoning, and the support of the next generation of capable, autonomous AI agents. Both models are now generally available in Amazon Bedrock, giving developers immediate access to both the model’s advanced reasoning and agentic capabilities.

Amazon Bedrock expands your AI choices with Anthropic’s most advanced models, giving you the freedom to build transformative applications with enterprise-grade security and responsible AI controls. Both models extend what’s possible with AI systems by improving task planning, tool use, and agent steerability.

With Opus 4’s advanced intelligence, you can build agents that handle long-running, high-context tasks like refactoring large codebases, synthesizing research, or coordinating cross-functional enterprise operations. Sonnet 4 is optimized for efficiency at scale, making it a strong fit as a subagent or for high-volume tasks like code reviews, bug fixes, and production-grade content generation.

When building with generative AI, many developers work on long-horizon tasks. These workflows require deep, sustained reasoning, often involving multistep processes, planning across large contexts, and synthesizing diverse inputs over extended timeframes. Good examples of these workflows are developer AI agents that help you to refactor or transform large projects. Existing models may respond quickly and fluently, but maintaining coherence and context over time—especially in areas like coding, research, or enterprise workflows—can still be challenging.

Claude Opus 4
Claude Opus 4 is the most advanced model to date from Anthropic, designed for building sophisticated AI agents that can reason, plan, and execute complex tasks with minimal oversight. Anthropic benchmarks show it is the best coding model available on the market today. It excels in software development scenarios where extended context, deep reasoning, and adaptive execution are critical. Developers can use Opus 4 to write and refactor code across entire projects, manage full-stack architectures, or design agentic systems that break down high-level goals into executable steps. It demonstrates strong performance on coding and agent-focused benchmarks like SWE-bench and TAU-bench, making it a natural choice for building agents that handle multistep development workflows. For example, Opus 4 can analyze technical documentation, plan a software implementation, write the required code, and iteratively refine it—while tracking requirements and architectural context throughout the process.

Claude Sonnet 4
Claude Sonnet 4 complements Opus 4 by balancing performance, responsiveness, and cost, making it well-suited for high-volume production workloads. It’s optimized for everyday development tasks with enhanced performance, such as powering code reviews, implementing bug fixes, and new feature development with immediate feedback loops. It can also power production-ready AI assistants for near real-time applications. Sonnet 4 is a drop-in replacement from Claude Sonnet 3.7. In multi-agent systems, Sonnet 4 performs well as a task-specific subagent—handling responsibilities like targeted code reviews, search and retrieval, or isolated feature development within a broader pipeline. You can also use Sonnet 4 to manage continuous integration and delivery (CI/CD) pipelines, perform bug triage, or integrate APIs, all while maintaining high throughput and developer-aligned output.

Opus 4 and Sonnet 4 are hybrid reasoning models offering two modes: near-instant responses and extended thinking for deeper reasoning. You can choose near-instant responses for interactive applications, or enable extended thinking when a request benefits from deeper analysis and planning. Thinking is especially useful for long-context reasoning tasks in areas like software engineering, math, or scientific research. By configuring the model’s thinking budget—for example, by setting a maximum token count—you can tune the tradeoff between latency and answer depth to fit your workload.

How to get started
To see Opus 4 or Sonnet 4 in action, enable the new model in your AWS account. Then, you can start coding using the Bedrock Converse API with model IDanthropic.claude-opus-4-20250514-v1:0 for Opus 4 and anthropic.claude-sonnet-4-20250514-v1:0 for Sonnet 4. We recommend using the Converse API, because it provides a consistent API that works with all Amazon Bedrock models that support messages. This means you can write code one time and use it with different models.

For example, let’s imagine I write an agent to review code before merging changes in a code repository. I write the following code that uses the Bedrock Converse API to send a system and user prompts. Then, the agent consumes the streamed result.

private let modelId = "us.anthropic.claude-sonnet-4-20250514-v1:0"

// Define the system prompt that instructs Claude how to respond
let systemPrompt = """
You are a senior iOS developer with deep expertise in Swift, especially Swift 6 concurrency. Your job is to perform a code review focused on identifying concurrency-related edge cases, potential race conditions, and misuse of Swift concurrency primitives such as Task, TaskGroup, Sendable, @MainActor, and @preconcurrency.

You should review the code carefully and flag any patterns or logic that may cause unexpected behavior in concurrent environments, such as accessing shared mutable state without proper isolation, incorrect actor usage, or non-Sendable types crossing concurrency boundaries.

Explain your reasoning in precise technical terms, and provide recommendations to improve safety, predictability, and correctness. When appropriate, suggest concrete code changes or refactorings using idiomatic Swift 6
"""
let system: BedrockRuntimeClientTypes.SystemContentBlock = .text(systemPrompt)

// Create the user message with text prompt and image
let userPrompt = """
Can you review the following Swift code for concurrency issues? Let me know what could go wrong and how to fix it.
"""
let prompt: BedrockRuntimeClientTypes.ContentBlock = .text(userPrompt)

// Create the user message with both text and image content
let userMessage = BedrockRuntimeClientTypes.Message(
    content: [prompt],
    role: .user
)

// Initialize the messages array with the user message
var messages: [BedrockRuntimeClientTypes.Message] = []
messages.append(userMessage)

// Configure the inference parameters
let inferenceConfig: BedrockRuntimeClientTypes.InferenceConfiguration = .init(maxTokens: 4096, temperature: 0.0)

// Create the input for the Converse API with streaming
let input = ConverseStreamInput(inferenceConfig: inferenceConfig, messages: messages, modelId: modelId, system: [system])

// Make the streaming request
do {
    // Process the stream
    let response = try await bedrockClient.converseStream(input: input)

    // Iterate through the stream events
    for try await event in stream {
        switch event {
        case .messagestart:
            print("AI-assistant started to stream"")

        case let .contentblockdelta(deltaEvent):
            // Handle text content as it arrives
            if case let .text(text) = deltaEvent.delta {
                self.streamedResponse + = text
                print(text, termination: "")
            }

        case .messagestop:
            print("\n\nStream ended")
            // Create a complete assistant message from the streamed response
            let assistantMessage = BedrockRuntimeClientTypes.Message(
                content: [.text(self.streamedResponse)],
                role: .assistant
            )
            messages.append(assistantMessage)

        default:
            break
        }
    }

To help you get started, my colleague Dennis maintains a broad range of code examples for multiple use cases and a variety of programming languages.

Available today in Amazon Bedrock
This release gives developers immediate access in Amazon Bedrock, a fully managed, serverless service, to the next generation of Claude models developed by Anthropic. Whether you’re already building with Claude in Amazon Bedrock or just getting started, this seamless access makes it faster to experiment, prototype, and scale with cutting-edge foundation models—without managing infrastructure or complex integrations.

Claude Opus 4 is available in the following AWS Regions in North America: US East (Ohio, N. Virginia) and US West (Oregon). Claude Sonnet 4 is available not only in AWS Regions in North America but also in APAC, and Europe: US East (Ohio, N. Virginia), US West (Oregon), Asia Pacific (Hyderabad, Mumbai, Osaka, Seoul, Singapore, Sydney, Tokyo), and Europe (Spain). You can access the two models through cross-Region inference. Cross-Region inference helps to automatically select the optimal AWS Region within your geography to process your inference request.

Opus 4 tackles your most challenging development tasks, while Sonnet 4 excels at routine work with its optimal balance of speed and capability.

Learn more about the pricing and how to use these new models in Amazon Bedrock today!

— seb

Empower financial analytics by creating structured knowledge bases using Amazon Bedrock and Amazon Redshift

Post Syndicated from Nita Shah original https://aws.amazon.com/blogs/big-data/empower-financial-analytics-by-creating-structured-knowledge-bases-using-amazon-bedrock-and-amazon-redshift/

Traditionally, financial data analysis could require deep SQL expertise and database knowledge. Now with Amazon Bedrock Knowledge Bases integration with structured data, you can use simple, natural language prompts to query complex financial datasets. By combining the AI capabilities of Amazon Bedrock with an Amazon Redshift data warehouse, individuals with varied levels of technical expertise can quickly generate valuable insights, making sure that data-driven decision-making is no longer limited to those with specialized programming skills.

With the support for structured data retrieval using Amazon Bedrock Knowledge Bases, you can now use natural language querying to retrieve structured data from your data sources, such as Amazon Redshift. This enables applications to seamlessly integrate natural language processing capabilities on structured data through simple API calls. Developers can rapidly implement sophisticated data querying features without complex coding—just connect to the API endpoints and let users explore financial data using plain English. From customer portals to internal dashboards and mobile apps, this API-driven approach makes enterprise-grade data analysis accessible to everyone in your organization. Using structured data from a Redshift data warehouse, you can efficiently and quickly build generative AI applications for tasks such as text generation, sentiment analysis, or data translation.

In this post, we showcase how financial planners, advisors, or bankers can now ask questions in natural language, such as, “Give me the name of the customer with the highest number of accounts?” or “Give me details of all accounts for a specific customer.” These prompts will receive precise data from the customer databases for accounts, investments, loans, and transactions. Amazon Bedrock Knowledge Bases automatically translates these natural language queries into optimized SQL statements, thereby accelerating time to insight, enabling faster discoveries and efficient decision-making.

Solution overview

To illustrate the new Amazon Bedrock Knowledge Bases integration with structured data in Amazon Redshift, we will build a conversational AI-powered assistant for financial assistance that is designed to help answer financial inquiries, like “Who has the most accounts?” or “Give details of the customer with the highest loan amount.”

We will build a solution using sample financial datasets and set up Amazon Redshift as the knowledge base. Users and applications will be able to access this information using natural language prompts.

The following diagram provides an overview of the solution.

For building and running this solution, the steps include:

  1. Load sample financial datasets.
  2. Enable Amazon Bedrock large language model (LLM) access for Amazon Nova Pro.
  3. Create an Amazon Bedrock knowledge base referencing structured data in Amazon Redshift.
  4. Ask queries and get responses in natural language.

To implement the solution, we use a sample financial dataset that is for demonstration purposes only. The same implementation approach can be adapted to your specific datasets and use cases.

Download the SQL script to run the implementation steps in Amazon Redshift Query Editor V2. If you’re using another SQL editor, you can copy and paste the SQL queries either from this post or from the downloaded notebook.

Prerequisites

Make sure your meet the following prerequisites:

  1. Have an AWS account.
  2. Create an Amazon Redshift Serverless workgroup or provisioned cluster. For setup instructions, see Creating a workgroup with a namespace or Create a sample Amazon Redshift database, respectively. The Amazon Bedrock integration feature is supported in both Amazon Redshift provisioned and serverless.
  3. Create an AWS Identity and Access Management (IAM) role. For instructions, see Creating or updating an IAM role for Amazon Redshift ML integration with Amazon Bedrock.
  4. Associate the IAM role to a Redshift instance.
  5. Set up the required permissions for Amazon Bedrock Knowledge Bases to connect with Amazon Redshift.

Load sample financial data

To load the finance datasets to Amazon Redshift, complete the following steps:

  1. Open the Amazon Redshift Query Editor V2 or another SQL editor of your choice and connect to the Redshift database.
  2. Run the following SQL to create the finance data tables and load sample data:
    -- Create table
    CREATE TABLE accounts (
        id integer ,
        account_id integer PRIMARY KEY,
        customer_id integer,
        account_type character varying(256),
        opening_date date,
        balance bigint,
        currency character varying(256)
    );
    
    CREATE TABLE customer (
        id integer,
        customer_id integer PRIMARY KEY ,
        name character varying(256) ,
        age integer,
        gender character varying(256) ,
        address character varying(256) ,
        phone character varying(256) ,
        email character varying(256)
    );
    
    CREATE TABLE investments (
        id integer ,
        investment_id integer PRIMARY KEY,
        customer_id integer ,
        investment_type character varying(256) ,
        investment_name character varying(256) ,
        purchase_date date ,
        purchase_price bigint ,
        quantity integer 
    );
    
    
    CREATE TABLE loans (
        id integer ,
        loan_id integer PRIMARY KEY,
        customer_id integer ,
        loan_type character varying(256) ,
        loan_amount bigint ,
        interest_rate integer ,
        start_date date ,
        end_date date 
    );
    
    CREATE TABLE orders (
        id integer ,
        order_id integer PRIMARY KEY,
        customer_id integer ,
        order_type character varying(256) ,
        order_date date ,
        investment_id integer ,
        quantity integer ,
        price integer 
    );
    
    CREATE TABLE transactions (
        id integer ,
        transaction_id integer PRIMARY KEY ,
        account_id integer REFERENCES accounts(account_id),
        transaction_type character varying(256) ,
        transaction_date date ,
        amount integer ,
        description character varying(256) 
    );

  3. Download the sample financial dataset to your local storage and unzip the zipped folder.
  4. Create an Amazon Simple Storage Service (Amazon S3) bucket with a unique name. For instructions, refer to Creating a general purpose bucket.
  5. Upload the downloaded files into your newly created S3 bucket.
  6. Using the following COPY command statements, load the datasets from Amazon S3 into the new tables you created in Amazon Redshift. Replace <<your_s3_bucket>> with the name of your S3 bucket and <<your_region>> with your AWS Region.
    -- Load sample data
    COPY accounts FROM 's3://<<your_s3_bucket>>/accounts.csv' IAM_ROLE DEFAULT FORMAT AS CSV DELIMITER ',' QUOTE '"' IGNOREHEADER 1 REGION AS '<<your_region>>';
    
    COPY customer FROM 's3://<<your_s3_bucket>>/customer.csv' IAM_ROLE DEFAULT FORMAT AS CSV DELIMITER ',' QUOTE '"' IGNOREHEADER 1 REGION AS '<<your_region>>';
    COPY investments FROM 's3://<<your_s3_bucket>>/investments.csv' IAM_ROLE DEFAULT FORMAT AS CSV DELIMITER ',' QUOTE '"' IGNOREHEADER 1 REGION AS '<<your_region>>';
    COPY loans FROM 's3://<<your_s3_bucket>>/loans.csv' IAM_ROLE DEFAULT FORMAT AS CSV DELIMITER ',' QUOTE '"' IGNOREHEADER 1 REGION AS '<<your_region>>';
    COPY orders FROM 's3://<<your_s3_bucket>>/orders.csv' IAM_ROLE DEFAULT FORMAT AS CSV DELIMITER ',' QUOTE '"' IGNOREHEADER 1 REGION AS '<<your_region>>';
    COPY transactions FROM 's3://<<your_s3_bucket>>/transactions.csv' IAM_ROLE DEFAULT FORMAT AS CSV DELIMITER ',' QUOTE '"' IGNOREHEADER 1 REGION AS '<<your_region>>';

Enable LLM access

With Amazon Bedrock, you can access state-of-the-art AI models from providers like Anthropic, AI21 Labs, Stability AI, and Amazon’s own foundation models (FMs). These include Anthropic’s Claude 2, which excels at complex reasoning and content generation; Jurassic-2 from AI21 Labs, known for its multilingual capabilities; Stable Diffusion from Stability AI for image generation; and Amazon Titan models for various text and embedding tasks. For this demo, we use Amazon Bedrock to access the Amazon Nova FMs. Specifically, we use the Amazon Nova Pro model, which is a highly capable multimodal model designed for a wide range of tasks like video summarization, Q&A, mathematical reasoning, software development, and AI agents, including high speed and accuracy for text summarization tasks.

Make sure you have the required IAM permissions to enable access to available Amazon Bedrock Nova FMs. Then complete the following steps to enable model access in Amazon Bedrock:

  1. On the Amazon Bedrock console, in the navigation pane, choose Model access.
  2. Choose Enable specific models.
  3. Search for Amazon Nova models, select Nova Pro, and choose Next.
  4. Review the selection and choose Submit.

Create an Amazon Bedrock knowledge base referencing structured data in Amazon Redshift

Amazon Bedrock Knowledge Bases uses Amazon Redshift as the query engine to query your data. It reads metadata from your structured data store to generate SQL queries. There are different supported authentication methods to create the Amazon Bedrock knowledge base using Amazon Redshift. For more information, refer to the Set up query engine for your structured data store in Amazon Bedrock Knowledge Bases.

For this post, we create an Amazon Bedrock knowledge base for the Redshift database and sync the data using IAM authentication.

If you’re creating an Amazon Bedrock knowledge base through the AWS Management Console, you can skip the service role setup mentioned in the previous section. It automatically creates one with the necessary permissions for Amazon Bedrock Knowledge Bases to retrieve data from your new knowledge base and generate SQL queries for structured data stores.

When creating an Amazon Bedrock knowledge base using an API, you must attach IAM policies that grant permissions to create and manage knowledge bases with connected data stores. Refer to Prerequisites for creating an Amazon Bedrock Knowledge Base with a structured data store for instructions.

Complete the following steps to create an Amazon Bedrock knowledge base using structured data:

  1. On the Amazon Bedrock console, choose Knowledge Bases in the navigation pane.
  2. Choose Create and choose Knowledge Base with structure data store from the dropdown menu.
  3. Provide the following details for your knowledge base:
    1. Enter a name and optional description.
    2. Select Amazon Redshift as the query engine.
    3. Select Create and use a new service role for resource management.
    4. Make note of this newly created IAM role.
    5. Choose Next to proceed to the next part of the setup process.
    6. Configure the query engine:
      • Select Redshift Serverless (Amazon Redshift provisioned is also supported).
      • Choose your Redshift workgroup.
      • Use the IAM role created earlier.
      • Under Default storage metadata, select Amazon Redshift databases and for Database, choose dev.
      • You can customize settings by adding specific contexts to enhance the accuracy of the results.
      • Choose Next.
    7. Complete creating your knowledge base.
    8. Record the generated service role details.
    9. Next, grant appropriate access to the service role for Amazon Bedrock Knowledge Bases through the Amazon Redshift Query Editor V2. Update <your Service Role name> in the following statements with your service role, and update the value for <your schema>.
      CREATE USER "IAMR:<your Service Role name>" WITH PASSWORD DISABLE;
      SELECT * FROM PG_USER; -- To verify that the user is created.
      GRANT SELECT ON ALL TABLES IN SCHEMA <your schema> TO "IAMR:<your Service Role name>";
      --You can also Restricting access to certain tables for finer-grained control on the tables that can be accessed as shown below
      GRANT SELECT ON TABLE customer to "IAMR:<your Service Role name>";
      GRANT SELECT ON TABLE loan to "IAMR:<your Service Role name>";

Now you can update the knowledge base with the Redshift database.

  1. On the Amazon Bedrock console, choose Knowledge Bases in the navigation pane.
  2. Open the knowledge base you created.
  3. Select the dev Redshift database and choose Sync.

It may take a few minutes for the status to display as COMPLETE.

Ask queries and get responses in natural language

You can set up your application to query the knowledge base or attach the knowledge base to an agent by deploying your knowledge base for your AI application. For this demo, we use a native testing interface on the Amazon Bedrock Knowledge Bases console.

To ask questions in natural language on the knowledge base for Redshift data, complete the following steps:

  1. On the Amazon Bedrock console, open the details page for your knowledge base.
  2. Choose Test.
  3. Choose your category (Amazon), model (Nova Pro), and inference settings (On demand), and choose Apply.
  4. In the right pane of the console, test the knowledge base setup with Amazon Redshift by asking a few simple questions in natural language, such as “How many tables do I have in the database?” or “Give me list of all tables in the database.

The following screenshot shows our results.

  1. To view the generated query from your Amazon Redshift based knowledge base, choose Show details next to the response.
  2. Next, ask questions related to the financial datasets loaded in Amazon Redshift using natural language prompts, such as, “Give me the name of the customer with the highest number of accounts” or “Give the details of all accounts for customer Deanna McCoy.

The following screenshot shows the responses in natural language.

Using natural language queries in Amazon Bedrock, you were able to retrieve responses from the structured financial data stored in Amazon Redshift.

Considerations

In this section, we discuss some important considerations when using this solution.

Security and compliance

When integrating Amazon Bedrock with Amazon Redshift, implementing robust security measures is crucial. To protect your systems and data, implement essential safeguards including restricted database roles, read-only database instances, and proper input validation. These measures help prevent unauthorized access and potential system vulnerabilities. For more information, see Allow your Amazon Bedrock Knowledge Bases service role to access your data store.

Cost

You incur a cost for converting natural language to text based on SQL. To learn more, refer to Amazon Bedrock pricing.

Use custom contexts

To improve query accuracy, you can enhance SQL generation by providing custom context in two key ways. First, specify which tables to include or exclude, focusing the model on relevant data structures. Second, supply curated queries as examples, demonstrating the types of SQL queries you expect. These curated queries serve as valuable reference points, guiding the model to generate more accurate and relevant SQL outputs tailored to your specific needs. For more information, refer to Create a knowledge base by connecting to a structured data store.

For different workgroups, you can create separate knowledge bases for each group, with access only to their specific tables. Control data access by setting up role-based permissions in Amazon Redshift, verifying each role can only view and query authorized tables.

Clean up

To avoid incurring future charges, delete the Redshift Serverless instance or provisioned data warehouse created as part of the prerequisite steps.

Conclusion

Generative AI applications provide significant advantages in structured data management and analysis. The key benefits include:

  • Using natural language processing – This makes data warehouses more accessible and user-friendly
  • Enhancing customer experience – By providing more intuitive data interactions, it boosts overall customer satisfaction and engagement
  • Simplifying data warehouse navigation – Users can understand and explore data warehouse content through natural language interactions, improving ease of use
  • Improving operational efficiency – By automating routine tasks, it allows human resources to focus on more complex and strategic activities

In this post, we showed how the natural language querying capabilities of Amazon Bedrock Knowledge Bases when integrated with Amazon Redshift enables rapid solution development. This is particularly valuable for the finance industry, where financial planners, advisors, or bankers face challenges in accessing and analyzing large volumes of financial data in a secured and performant manner.

By enabling natural language interactions, you can bypass the traditional barriers of understanding database structures and SQL queries, and quickly access insights and provide real-time support. This streamlined approach accelerates decision-making and drives innovation by making complex data analysis accessible to non-technical users.

For additional details on Amazon Bedrock and Amazon Redshift integration, refer to Amazon Redshift ML integration with Amazon Bedrock.


About the authors

Nita Shah is an Analytics Specialist Solutions Architect at AWS based out of New York. She has been building data warehouse solutions for over 20 years and specializes in Amazon Redshift. She is focused on helping customers design and build enterprise-scale well-architected analytics and decision support platforms.

Sushmita Barthakur is a Senior Data Solutions Architect at Amazon Web Services (AWS), supporting Strategic customers architect their data workloads on AWS. With a background in data analytics, she has extensive experience helping customers architect and build enterprise data lakes, ETL workloads, data warehouses and data analytics solutions, both on-premises and the cloud. Sushmita is based in Florida and enjoys traveling, reading and playing tennis.

Jonathan Katz is a Principal Product Manager – Technical on the Amazon Redshift team and is based in New York. He is a Core Team member of the open source PostgreSQL project and an active open source contributor, including PostgreSQL and the pgvector project.

Llama 4 models from Meta now available in Amazon Bedrock serverless

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/llama-4-models-from-meta-now-available-in-amazon-bedrock-serverless/

The newest AI models from Meta, Llama 4 Scout 17B and Llama 4 Maverick 17B, are now available as a fully managed, serverless option in Amazon Bedrock. These new foundation models (FMs) deliver natively multimodal capabilities with early fusion technology that you can use for precise image grounding and extended context processing in your applications.

Llama 4 uses an innovative mixture-of-experts (MoE) architecture that provides enhanced performance across reasoning and image understanding tasks while optimizing for both cost and speed. This architectural approach enables Llama 4 to offer improved performance at lower cost compared to Llama 3, with expanded language support for global applications.

The models were already available on Amazon SageMaker JumpStart, and you can now use them in Amazon Bedrock to streamline building and scaling generative AI applications with enterprise-grade security and privacy.

Llama 4 Maverick 17B – A natively multimodal model featuring 128 experts and 400 billion total parameters. It excels in image and text understanding, making it suitable for versatile assistant and chat applications. The model supports a 1 million token context window, giving you the flexibility to process lengthy documents and complex inputs.

Llama 4 Scout 17B – A general-purpose multimodal model with 16 experts, 17 billion active parameters, and 109 billion total parameters that delivers superior performance compared to all previous Llama models. Amazon Bedrock currently supports a 3.5 million token context window for Llama 4 Scout, with plans to expand in the near future.

Use cases for Llama 4 models
You can use the advanced capabilities of Llama 4 models for a wide range of use cases across industries:

Enterprise applications – Build intelligent agents that can reason across tools and workflows, process multimodal inputs, and deliver high-quality responses for business applications.

Multilingual assistants – Create chat applications that understand images and provide high-quality responses across multiple languages, making them accessible to global audiences.

Code and document intelligence – Develop applications that can understand code, extract structured data from documents, and provide insightful analysis across large volumes of text and code.

Customer support – Enhance support systems with image analysis capabilities, enabling more effective problem resolution when customers share screenshots or photos.

Content creation – Generate creative content across multiple languages, with the ability to understand and respond to visual inputs.

Research – Build research applications that can integrate and analyze multimodal data, providing insights across text and images.

Using Llama 4 models in Amazon Bedrock
To use these new serverless models in Amazon Bedrock, I first need to request access. In the Amazon Bedrock console, I choose Model access from the navigation pane to toggle access to Llama 4 Maverick 17B and Llama 4 Scout 17B models.

Console screenshot.

The Llama 4 models can be easily integrated into your applications using the Amazon Bedrock Converse API, which provides a unified interface for conversational AI interactions.

Here’s an example of how to use the AWS SDK for Python (Boto3) with Llama 4 Maverick for a multimodal conversation:

import boto3
import json
import os

AWS_REGION = "us-west-2"
MODEL_ID = "us.meta.llama4-maverick-17b-instruct-v1:0"
IMAGE_PATH = "image.jpg"


def get_file_extension(filename: str) -> str:
    """Get the file extension."""
    extension = os.path.splitext(filename)[1].lower()[1:] or 'txt'
    if extension == 'jpg':
        extension = 'jpeg'
    return extension


def read_file(file_path: str) -> bytes:
    """Read a file in binary mode."""
    try:
        with open(file_path, 'rb') as file:
            return file.read()
    except Exception as e:
        raise Exception(f"Error reading file {file_path}: {str(e)}")

bedrock_runtime = boto3.client(
    service_name="bedrock-runtime",
    region_name=AWS_REGION
)

request_body = {
    "messages": [
        {
            "role": "user",
            "content": [
                {
                    "text": "What can you tell me about this image?"
                },
                {
                    "image": {
                        "format": get_file_extension(IMAGE_PATH),
                        "source": {"bytes": read_file(IMAGE_PATH)},
                    }
                },
            ],
        }
    ]
}

response = bedrock_runtime.converse(
    modelId=MODEL_ID,
    messages=request_body["messages"]
)

print(response["output"]["message"]["content"][-1]["text"])

This example demonstrates how to send both text and image inputs to the model and receive a conversational response. The Converse API abstracts away the complexity of working with different model input formats, providing a consistent interface across models in Amazon Bedrock.

For more interactive use cases, you can also use the streaming capabilities of the Converse API:

response_stream = bedrock_runtime.converse_stream(
    modelId=MODEL_ID,
    messages=request_body['messages']
)

stream = response_stream.get('stream')
if stream:
    for event in stream:

        if 'messageStart' in event:
            print(f"\nRole: {event['messageStart']['role']}")

        if 'contentBlockDelta' in event:
            print(event['contentBlockDelta']['delta']['text'], end="")

        if 'messageStop' in event:
            print(f"\nStop reason: {event['messageStop']['stopReason']}")

        if 'metadata' in event:
            metadata = event['metadata']
            if 'usage' in metadata:
                print(f"Usage: {json.dumps(metadata['usage'], indent=4)}")
            if 'metrics' in metadata:
                print(f"Metrics: {json.dumps(metadata['metrics'], indent=4)}")

With streaming, your applications can provide a more responsive experience by displaying model outputs as they are generated.

Things to know
The Llama 4 models are available today with a fully managed, serverless experience in Amazon Bedrock in the US East (N. Virginia) and US West (Oregon) AWS Regions. You can also access Llama 4 in US East (Ohio) via cross-region inference.

As usual with Amazon Bedrock, you pay for what you use. For more information, see Amazon Bedrock pricing.

These models support 12 languages for text (English, French, German, Hindi, Italian, Portuguese, Spanish, Thai, Arabic, Indonesian, Tagalog, and Vietnamese) and English when processing images.

To start using these new models today, visit the Meta Llama models section in the Amazon Bedrock User Guide. You can also explore how our Builder communities are using Amazon Bedrock in their solutions in the generative AI section of our community.aws site.

Danilo


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Writer Palmyra X5 and X4 foundation models are now available in Amazon Bedrock

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/writer-palmyra-x5-and-x4-foundation-models-are-now-available-in-amazon-bedrock/

One thing we’ve witnessed in recent months is the expansion of context windows in foundation models (FMs), with many now handling sequence lengths that would have been unimaginable just a year ago. However, building AI-powered applications that can process vast amounts of information while maintaining the reliability and security standards required for enterprise use remains challenging.

For these reasons, we’re excited to announce that Writer Palmyra X5 and X4 models are available today in Amazon Bedrock as a fully managed, serverless offering. AWS is the first major cloud provider to deliver fully managed models from Writer. Palmyra X5 is a new model launched today by Writer. Palmyra X4 was previously available in Amazon Bedrock Marketplace.

Writer Palmyra models offer robust reasoning capabilities that support complex agent-based workflows while maintaining enterprise security standards and reliability. Palmyra X5 features a one million token context window, and Palmyra X4 supports a 128K token context window. With these extensive context windows, these models remove some of the traditional constraints for app and agent development, enabling deeper analysis and more comprehensive task completion.

With this launch, Amazon Bedrock continues to bring access to the most advanced models and the tools you need to build generative AI applications with security, privacy, and responsible AI.

As a pioneer in FM development, Writer trains and fine-tunes its industry leading models on Amazon SageMaker HyperPod. With its optimized distributed training environment, Writer reduces training time and brings its models to market faster.

Palmyra X5 and X4 use cases
Writer Palmyra X5 and X4 are designed specifically for enterprise use cases, combining powerful capabilities with stringent security measures, including System and Organization Controls (SOC) 2, Payment Card Industry Data Security Standard (PCI DSS), and Health Insurance Portability and Accountability Act (HIPAA) compliance certifications.

Palmyra X5 and X4 models excel in various enterprise use cases across multiple industries:

Financial services – Palmyra models power solutions across investment banking and asset and wealth management, including deal transaction support, 10-Q, 10-K and earnings transcript highlights, fund and market research, and personalized client outreach at scale.

Healthcare and life science – Payors and providers use Palmyra models to build solutions for member acquisition and onboarding, appeals and grievances, case and utilization management, and employer request for proposal (RFP) response. Pharmaceutical companies use these models for commercial applications, medical affairs, R&D, and clinical trials.

Retail and consumer goods – Palmyra models enable AI solutions for product description creation and variation, performance analysis, SEO updates, brand and compliance reviews, automated campaign workflows, and RFP analysis and response.

Technology – Companies across the technology sector implement Palmyra models for personalized and account-based marketing, content creation, campaign workflow automation, account preparation and research, knowledge support, job briefs and candidate reports, and RFP responses.

Palmyra models support a comprehensive suite of enterprise-grade capabilities, including:

Adaptive thinking – Hybrid models combining advanced reasoning with enterprise-grade reliability, excelling at complex problem-solving and sophisticated decision-making processes.

Multistep tool-calling – Support for advanced tool-calling capabilities that can be used in complex multistep workflows and agentic actions, including interaction with enterprise systems to perform tasks like updating systems, executing transactions, sending emails, and triggering workflows.

Enterprise-grade reliability – Consistent, accurate results while maintaining strict quality standards required for enterprise use, with models specifically trained on business content to align outputs with professional standards.

Using Palmyra X5 and X4 in Amazon Bedrock
As for all new serverless models in Amazon Bedrock, I need to request access first. In the Amazon Bedrock console, I choose Model access from the navigation pane to enable access to Palmyra X5 and Palmyra X4 models.

Console screenshot

When I have access to the models, I can start building applications with any AWS SDKs using the Amazon Bedrock Converse API. The models use cross-Region inference with these inference profiles:

  • For Palmyra X5: us.writer.palmyra-x5-v1:0
  • For Palmyra X4: us.writer.palmyra-x4-v1:0

Here’s a sample implementation with the AWS SDK for Python (Boto3). In this scenario, there is a new version of an existing product. I need to prepare a detailed comparison of what’s new. I have the old and new product manuals. I use the large input context of Palmyra X5 to read and compare the two versions of the manual and prepare a first draft of the comparison document.

import sys
import os
import boto3
import re

AWS_REGION = "us-west-2"
MODEL_ID = "us.writer.palmyra-x5-v1:0"
DEFAULT_OUTPUT_FILE = "product_comparison.md"

def create_bedrock_runtime_client(region: str = AWS_REGION):
    """Create and return a Bedrock client."""
    return boto3.client('bedrock-runtime', region_name=region)

def get_file_extension(filename: str) -> str:
    """Get the file extension."""
    return os.path.splitext(filename)[1].lower()[1:] or 'txt'

def sanitize_document_name(filename: str) -> str:
    """Sanitize document name."""
    # Remove extension and get base name
    name = os.path.splitext(filename)[0]
    
    # Replace invalid characters with space
    name = re.sub(r'[^a-zA-Z0-9\s\-\(\)\[\]]', ' ', name)
    
    # Replace multiple spaces with single space
    name = re.sub(r'\s+', ' ', name)
    
    # Strip leading/trailing spaces
    return name.strip()

def read_file(file_path: str) -> bytes:
    """Read a file in binary mode."""
    try:
        with open(file_path, 'rb') as file:
            return file.read()
    except Exception as e:
        raise Exception(f"Error reading file {file_path}: {str(e)}")

def generate_comparison(client, document1: bytes, document2: bytes, filename1: str, filename2: str) -> str:
    """Generate a markdown comparison of two product manuals."""
    print(f"Generating comparison for {filename1} and {filename2}")
    try:
        response = client.converse(
            modelId=MODEL_ID,
            messages=[
                {
                    "role": "user",
                    "content": [
                        {
                            "text": "Please compare these two product manuals and create a detailed comparison in markdown format. Focus on comparing key features, specifications, and highlight the main differences between the products."
                        },
                        {
                            "document": {
                                "format": get_file_extension(filename1),
                                "name": sanitize_document_name(filename1),
                                "source": {
                                    "bytes": document1
                                }
                            }
                        },
                        {
                            "document": {
                                "format": get_file_extension(filename2),
                                "name": sanitize_document_name(filename2),
                                "source": {
                                    "bytes": document2
                                }
                            }
                        }
                    ]
                }
            ]
        )
        return response['output']['message']['content'][0]['text']
    except Exception as e:
        raise Exception(f"Error generating comparison: {str(e)}")

def main():
    if len(sys.argv) < 3 or len(sys.argv) > 4:
        cmd = sys.argv[0]
        print(f"Usage: {cmd} <manual1_path> <manual2_path> [output_file]")
        sys.exit(1)

    manual1_path = sys.argv[1]
    manual2_path = sys.argv[2]
    output_file = sys.argv[3] if len(sys.argv) == 4 else DEFAULT_OUTPUT_FILE
    paths = [manual1_path, manual2_path]

    # Check each file's existence
    for path in paths:
        if not os.path.exists(path):
            print(f"Error: File does not exist: {path}")
            sys.exit(1)

    try:
        # Create Bedrock client
        bedrock_runtime = create_bedrock_runtime_client()

        # Read both manuals
        print("Reading documents...")
        manual1_content = read_file(manual1_path)
        manual2_content = read_file(manual2_path)

        # Generate comparison directly from the documents
        print("Generating comparison...")
        comparison = generate_comparison(
            bedrock_runtime,
            manual1_content,
            manual2_content,
            os.path.basename(manual1_path),
            os.path.basename(manual2_path)
        )

        # Save comparison to file
        with open(output_file, 'w') as f:
            f.write(comparison)

        print(f"Comparison generated successfully! Saved to {output_file}")

    except Exception as e:
        print(f"Error: {str(e)}")
        sys.exit(1)

if __name__ == "__main__":
    main()

To learn how to use Amazon Bedrock with AWS SDKs, browse the code samples in the Amazon Bedrock User Guide.

Things to know
Writer Palmyra X5 and X4 models are available in Amazon Bedrock today in the US West (Oregon) AWS Region with cross-Region inference. For the most up-to-date information on model support by Region, refer to the Amazon Bedrock documentation. For information on pricing, visit Amazon Bedrock pricing.

These models support English, Spanish, French, German, Chinese, and multiple other languages, making them suitable for global enterprise applications.

Using the expansive context capabilities of these models, developers can build more sophisticated applications and agents that can process extensive documents, perform complex multistep reasoning, and handle sophisticated agentic workflows.

To start using Writer Palmyra X5 and X4 models today, visit the Writer model section in the Amazon Bedrock User Guide. You can also explore how our Builder communities are using Amazon Bedrock in their solutions in the generative AI section of our community.aws site.

Let us know what you build with these powerful new capabilities!

Danilo


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Introducing Amazon Nova Sonic: Human-like voice conversations for generative AI applications

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/introducing-amazon-nova-sonic-human-like-voice-conversations-for-generative-ai-applications/

Voice interfaces are essential to enhance customer experience in different areas such as customer support call automation, gaming, interactive education, and language learning. However, there are challenges when building voice-enabled applications.

Traditional approaches in building voice-enabled applications require complex orchestration of multiple models, such as speech recognition to convert speech to text, language models to understand and generate responses, and text-to-speech to convert text back to audio.

This fragmented approach not only increases development complexity but also fails to preserve crucial linguistic context such as tone, prosody, and speaking style that are essential for natural conversations. This can affect conversational AI applications that need low latency and nuanced understanding of verbal and non-verbal cues for fluid dialog handling and natural turn-taking.

To streamline the implementation of speech-enabled applications, today we are introducing Amazon Nova Sonic, the newest addition to the Amazon Nova family of foundation models (FMs) available in Amazon Bedrock.

Amazon Nova Sonic unifies speech understanding and generation into a single model that developers can use to create natural, human-like conversational AI experiences with low latency and industry-leading price performance. This integrated approach streamlines development and reduces complexity when building conversational applications.

Its unified model architecture delivers expressive speech generation and real-time text transcription without requiring a separate model. The result is an adaptive speech response that dynamically adjusts its delivery based on prosody, such as pace and timbre, of input speech.

When using Amazon Nova Sonic, developers have access to function calling (also known as tool use) and agentic workflows to interact with external services and APIs and perform tasks in the customer’s environment, including knowledge grounding with enterprise data using Retrieval-Augmented Generation.

At launch, Amazon Nova Sonic provides robust speech understanding for American and British English across various speaking styles and acoustic conditions, with additional languages coming soon.

Amazon Nova Sonic is developed with responsible AI at the forefront of innovation, featuring built-in protections for content moderation and watermarking.

Amazon Nova Sonic in action
The scenario for this demo is a contact center in the telecommunication industry. A customer reaches out to improve their subscription plan, and Amazon Nova Sonic handles the conversation.

With tool use, the model can interact with other systems and use agentic RAG with Amazon Bedrock Knowledge Bases to gather updated, customer-specific information such as account details, subscription plans, and pricing info.

The demo shows streaming transcription of speech input and displays streaming speech responses as text. The sentiment of the conversation is displayed in two ways: a time chart illustrating how it evolves, and a pie chart representing the overall distribution. There’s also an AI insights section providing contextual tips for a call center agent. Other interesting metrics shown in the web interface are the overall talk time distribution between the customer and the agent, and the average response time.

During the conversation with the support agent, you can observe through the metrics and hear in the voices how customer sentiment improves.

The video includes an example of how Amazon Nova Sonic handles interruptions smoothly, stopping to listen and then continuing the conversation in a natural way.

Now, let’s explore how you can integrate voice capabilities in your applications.

Using Amazon Nova Sonic
To get started with Amazon Nova Sonic, you first need to toggle model access in the Amazon Bedrock console, similar to how you would enable other FMs. Navigate to the Model access section of the navigation pane, find Amazon Nova Sonic under the Amazon models, and enable it for your account.

Amazon Bedrock provides a new bidirectional streaming API (InvokeModelWithBidirectionalStream) to help you implement real-time, low-latency conversational experiences on top of the HTTP/2 protocol. With this API, you can stream audio input to the model and receive audio output in real time, so that the conversation flows naturally.

You can use Amazon Nova Sonic with the new API with this model ID: amazon.nova-sonic-v1:0

After the session initialization, where you can configure inference parameters, the model operate through an event-driven architecture on both the input and output streams.

There are three key event types in the input stream:

System prompt – To set the overall system prompt for the conversation

Audio input streaming – To process continuous audio input in real-time

Tool result handling – To send the result of tool use calls back to the model (after tool use is requested in the output events)

Similarly, there are three groups of events in the output streams:

Automatic speech recognition (ASR) streaming – Speech-to-text transcript is generated, containing the result of realtime speech recognition.

Tool use handling – If there are a tool use events, they need to be handled using the information provided here, and the results sent back as input events.

Audio output streaming – To play output audio in real-time, a buffer is needed, because Amazon Nova Sonic model generates audio faster than real-time playback.

You can find examples of using Amazon Nova Sonic in the Amazon Nova model cookbook repository.

Prompt engineering for speech
When crafting prompts for Amazon Nova Sonic, your prompts should optimize content for auditory comprehension rather than visual reading, focusing on conversational flow and clarity when heard rather than seen.

When defining roles for your assistant, focus on conversational attributes (such as warm, patient, concise) rather than text-oriented attributes (detailed, comprehensive, systematic). A good baseline system prompt might be:

You are a friend. The user and you will engage in a spoken dialog exchanging the transcripts of a natural real-time conversation. Keep your responses short, generally two or three sentences for chatty scenarios.

More generally, when creating prompts for speech models, avoid requesting visual formatting (such as bullet points, tables, or code blocks), voice characteristic modifications (accent, age, or singing), or sound effects.

Things to know
Amazon Nova Sonic is available today in the US East (N. Virginia) AWS Region. Visit Amazon Bedrock pricing to see the pricing models.

Amazon Nova Sonic can understand speech in different speaking styles and generates speech in expressive voices, including both masculine-sounding and feminine-sounding voices, in different English accents, including American and British. Support for additional languages will be coming soon.

Amazon Nova Sonic handles user interruptions gracefully without dropping the conversational context and is robust to background noise. The model supports a context window of 32K tokens for audio with a rolling window to handle longer conversations and has a default session limit of 8 minutes.

The following AWS SDKs support the new bidirectional streaming API:

Python developers can use this new experimental SDK that makes it easier to use the bidirectional streaming capabilities of Amazon Nova Sonic. We’re working to add support to the other AWS SDKs.

I’d like to thank Reilly Manton and Chad Hendren, who set up the demo with the contact center in the telecommunication industry, and Anuj Jauhari, who helped me understand the rich landscape in which speech-to-speech models are being deployed.

To learn more, these articles that enter into the details of how to use the new bidirectional streaming API with compelling demos:

Whether you’re creating customer service solutions, language learning applications, or other conversational experiences, Amazon Nova Sonic provides the foundation for natural, engaging voice interactions. To get started, visit the Amazon Bedrock console today. To learn more, visit the Amazon Nova section of the user guide.

Danilo


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

DeepSeek-R1 now available as a fully managed serverless model in Amazon Bedrock

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/deepseek-r1-now-available-as-a-fully-managed-serverless-model-in-amazon-bedrock/

As of January 30, DeepSeek-R1 models became available in Amazon Bedrock through the Amazon Bedrock Marketplace and Amazon Bedrock Custom Model Import. Since then, thousands of customers have deployed these models in Amazon Bedrock. Customers value the robust guardrails and comprehensive tooling for safe AI deployment. Today, we’re making it even easier to use DeepSeek in Amazon Bedrock through an expanded range of options, including a new serverless solution.

The fully managed DeepSeek-R1 model is now generally available in Amazon Bedrock. Amazon Web Services (AWS) is the first cloud service provider (CSP) to deliver DeepSeek-R1 as a fully managed, generally available model. You can accelerate innovation and deliver tangible business value with DeepSeek on AWS without having to manage infrastructure complexities. You can power your generative AI applications with DeepSeek-R1’s capabilities using a single API in the Amazon Bedrock’s fully managed service and get the benefit of its extensive features and tooling.

According to DeepSeek, their model is publicly available under MIT license and offers strong capabilities in reasoning, coding, and natural language understanding. These capabilities power intelligent decision support, software development, mathematical problem-solving, scientific analysis, data insights, and comprehensive knowledge management systems.

As is the case for all AI solutions, give careful consideration to data privacy requirements when implementing in your production environments, check for bias in output, and monitor your results. When implementing publicly available models like DeepSeek-R1, consider the following:

  • Data security – You can access the enterprise-grade security, monitoring, and cost control features of Amazon Bedrock that are essential for deploying AI responsibly at scale, all while retaining complete control over your data. Users’ inputs and model outputs aren’t shared with any model providers. You can use these key security features by default, including data encryption at rest and in transit, fine-grained access controls, secure connectivity options, and download various compliance certifications while communicating with the DeepSeek-R1 model in Amazon Bedrock.
  • Responsible AI – You can implement safeguards customized to your application requirements and responsible AI policies with Amazon Bedrock Guardrails. This includes key features of content filtering, sensitive information filtering, and customizable security controls to prevent hallucinations using contextual grounding and Automated Reasoning checks. This means you can control the interaction between users and the DeepSeek-R1 model in Bedrock with your defined set of policies by filtering undesirable and harmful content in your generative AI applications.
  • Model evaluation – You can evaluate and compare models to identify the optimal model for your use case, including DeepSeek-R1, in a few steps through either automatic or human evaluations by using Amazon Bedrock model evaluation tools. You can choose automatic evaluation with predefined metrics such as accuracy, robustness, and toxicity. Alternatively, you can choose human evaluation workflows for subjective or custom metrics such as relevance, style, and alignment to brand voice. Model evaluation provides built-in curated datasets, or you can bring in your own datasets.

We strongly recommend integrating Amazon Bedrock Guardrails and using Amazon Bedrock model evaluation features with your DeepSeek-R1 model to add robust protection for your generative AI applications. To learn more, visit Protect your DeepSeek model deployments with Amazon Bedrock Guardrails and Evaluate the performance of Amazon Bedrock resources.

Get started with the DeepSeek-R1 model in Amazon Bedrock
If you’re new to using DeepSeek-R1 models, go to the Amazon Bedrock console, choose Model access under Bedrock configurations in the left navigation pane. To access the fully managed DeepSeek-R1 model, request access for DeepSeek-R1 in DeepSeek. You’ll then be granted access to the model in Amazon Bedrock.

Next, to test the DeepSeek-R1 model in Amazon Bedrock, choose Chat/Text under Playgrounds in the left menu pane. Then choose Select model in the upper left, and select DeepSeek as the category and DeepSeek-R1 as the model. Then choose Apply.

Using the selected DeepSeek-R1 model, I run the following prompt example:

A family has $5,000 to save for their vacation next year. They can place the money in a savings account earning 2% interest annually or in a certificate of deposit earning 4% interest annually but with no access to the funds until the vacation. If they need $1,000 for emergency expenses during the year, how should they divide their money between the two options to maximize their vacation fund?

This prompt requires a complex chain of thought and produces very precise reasoning results.

To learn more about usage recommendations for prompts, refer to the README of the DeepSeek-R1 model in its GitHub repository.

By choosing View API request, you can also access the model using code examples in the AWS Command Line Interface (AWS CLI) and AWS SDK. You can use us.deepseek.r1-v1:0 as the model ID.

Here is a sample of the AWS CLI command:

aws bedrock-runtime invoke-model \
     --model-id us.deepseek-r1-v1:0 \
     --body "{\"messages\":[{\"role\":\"user\",\"content\":[{\"type\":\"text\",\"text\":\"[n\"}]}],max_tokens\":2000,\"temperature\":0.6,\"top_k\":250,\"top_p\":0.9,\"stop_sequences\":[\"\\n\\nHuman:\"]}" \
     --cli-binary-format raw-in-base64-out \
     --region us-west-2 \
     invoke-model-output.txt

The model supports both the InvokeModel and Converse API. The following Python code examples show how to send a text message to the DeepSeek-R1 model using the Amazon Bedrock Converse API for text generation.

import boto3
from botocore.exceptions import ClientError

# Create a Bedrock Runtime client in the AWS Region you want to use.
client = boto3.client("bedrock-runtime", region_name="us-west-2")

# Set the model ID, e.g., Llama 3 8b Instruct.
model_id = "us.deepseek.r1-v1:0"

# Start a conversation with the user message.
user_message = "Describe the purpose of a 'hello world' program in one line."
conversation = [
    {
        "role": "user",
        "content": [{"text": user_message}],
    }
]

try:
    # Send the message to the model, using a basic inference configuration.
    response = client.converse(
        modelId=model_id,
        messages=conversation,
        inferenceConfig={"maxTokens": 2000, "temperature": 0.6, "topP": 0.9},
    )

    # Extract and print the response text.
    response_text = response["output"]["message"]["content"][0]["text"]
    print(response_text)

except (ClientError, Exception) as e:
    print(f"ERROR: Can't invoke '{model_id}'. Reason: {e}")
    exit(1)

To enable Amazon Bedrock Guardrails on the DeepSeek-R1 model, select Guardrails under Safeguards in the left navigation pane, and create a guardrail by configuring as many filters as you need. For example, if you filter for “politics” word, your guardrails will recognize this word in the prompt and show you the blocked message.

4. Apply the Bedrock Guardrails to the DeepSeek-R1 model

You can test the guardrail with different inputs to assess the guardrail’s performance. You can refine the guardrail by setting denied topics, word filters, sensitive information filters, and blocked messaging until it matches your needs.

To learn more about Amazon Bedrock Guardrails, visit Stop harmful content in models using Amazon Bedrock Guardrails in the AWS documentation or other deep dive blog posts about Amazon Bedrock Guardrails on the AWS Machine Learning Blog channel.

Here’s a demo walkthrough highlighting how you can take advantage of the fully managed DeepSeek-R1 model in Amazon Bedrock:

Now available
DeepSeek-R1 is now available fully managed in Amazon Bedrock in the US East (N. Virginia), US East (Ohio), and US West (Oregon) AWS Regions through cross-Region inference. Check the full Region list for future updates. To learn more, check out the DeepSeek in Amazon Bedrock product page and the Amazon Bedrock pricing page.

Give the DeepSeek-R1 model a try in the Amazon Bedrock console today and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

Channy

Updated on March 10, 2025 — Fixed a screenshot of model selection and model ID.

Training a call center fraud detection model for IVR calls with Amazon SageMaker Canvas

Post Syndicated from Pablo Forero original https://aws.amazon.com/blogs/architecture/training-a-call-center-fraud-detection-model-for-ivr-calls-with-amazon-sagemaker-canvas/

Fraud detection is a critical challenge for call centers, they need to provide a seamless customer experience while protecting the organization from fraudulent activities. Traditionally, call centers have relied on agents to manually screen calls, which can be time-consuming and expensive. Alternatively, companies might force customers to authenticate themselves every time they call, leading to a poor user experience. Machine learning (ML) offers a powerful solution that can help organization reach a harmonious balance between these approaches, enabling efficient and accurate fraud detection without compromising the customer experience.

This blog post will show you how to use the power of ML to build a fraud-detection model using Amazon SageMaker Canvas, a no-code/low-code ML service that business analysts and domain experts can use to build, train, and deploy ML models without requiring extensive ML expertise.

Background

In this solution, you will use a contact trace record (CTR) dataset from Amazon Connect. The solution works with data from other inbound telephony services provided they contain call specific metadata. Importantly, each call has been previously labeled based on past fraud detection efforts by the call center.

To start, you will enrich the raw CTR data using the phone number validation service from Amazon Pinpoint. Then, you will prepare the data using Amazon SageMaker notebooks and train a fraud detection model using SageMaker Canvas. Finally, to understand how to provide a scalable and cost-effective solution, you will explore how to deploy the model to a Sagemaker endpoint and right-size through autoscaling in a managed, serverless environment.

The following figure shows the architecture with the complete process including data enrichment, merging, cleanup, and model training and deployment. Throughout this blogpost we will reference the key parts as we implement them.

Architecture diagram

Data enrichment and preparation

Each CTR contains information about an incoming call such as agent, connection attempts, and channel. Before proceeding, you must transform the data into a tabular form (CSV, Parquet, or tables), which are the supported formats in SageMaker Canvas.

The raw CTR dataset doesn’t contain enough information to effectively train an ML model. You will enrich it using the Amazon Pinpoint validate API, which provides additional fields such as carrier, location data, and phone type. After you have the enriched dataset, you can use a SageMaker notebook to clean and prepare the data for training.

Enriching the data with Amazon Pinpoint validate API
Amazon Pinpoint includes a phone number validation service that you can use to determine if a phone number is valid and to obtain additional contact information. For example, the API response for a valid mobile phone number would look like the following:

{
    "NumberValidateResponse": {
        "Carrier": "ExampleCorp Mobile",
        "City": "Seattle",
        "CleansedPhoneNumberE164": "+12065550142",
        "CleansedPhoneNumberNational": "2065550142",
        "Country": "United States",
        "CountryCodeIso2": "US",
        "CountryCodeNumeric": "1",
        "OriginalPhoneNumber": "+12065550142",
        "PhoneType": "MOBILE",
        "PhoneTypeCode": 0,
        "Timezone": "America/Los_Angeles",
        "ZipCode": "98101"
    }
}

While the response for an invalid phone number would contain the following:

{
    "NumberValidateResponse": {
        "CleansedPhoneNumberE164": "+44163296076",
        "CleansedPhoneNumberNational": "163296076",
        "Country": "United Kingdom",
        "CountryCodeIso2": "GB",
        "CountryCodeNumeric": "44",
        "OriginalPhoneNumber": "+440163296076",
        "PhoneType": "INVALID",
        "PhoneTypeCode": 3
    }
}

There are multiple ways to enrich your dataset with this API. The response from the validate API call is a JSON document that contains all the fields. You will need to convert them to the appropriate format and merge them with the original CTR dataset. This will give you an enriched dataset that includes all the fields from the CTR and their corresponding validate results. The goal is to extract the caller phone number from each row in the dataset (CustomerEndpoint in Connect) and run it against the Amazon Pinpoint validate API.

The following figure shows an example architecture used to enrich with Amazon Pinpoint, cache in Amazon DynamoDB, and merge the datasets with Lambda functions. The DynamoDB cache saves the responses from Pinpoint by input key so that you don’t have to re-validate phone numbers.

Portion of the architecture focusing on the validation process

Data engineering and data preparation

The first step is to clean up the data by discarding fields that aren’t adding any predictive value. This will make the training process faster and the model more accurate. For example, in the CTR data, the AWSAccountId field will be the same for all records, and the ContactId field will be unique, so you can discard them both. The goal is to simplify the dataset as much as possible using SageMaker Canvas to perform multiple experiments to better understand which fields in the data have the biggest impact on the prediction.

After you have reduced the dataset, you can select a random, smaller subset of data (for example, 1,000 records) and build a model in SageMaker Canvas. SageMaker Canvas provides a visual interface that you can use to rapidly build, train, and deploy ML models without the need for extensive coding.

To begin the training process, you will first import the prepared, enriched data file containing the CTR data into SageMaker Canvas. SageMaker Canvas will automatically detect the data format and structure, allowing you to preview the dataset and make any necessary adjustments before proceeding.

After the dataset is ready, you can select the fraud label as your target variable and configure the model training parameters. SageMaker Canvas will handle the underlying ML algorithms and hyperparameter tuning, streamlining the model development process.

After the model is trained, SageMaker Canvas will show an analysis of the fields and their weights. In addition to the build step—where you can drop and transform your imported dataset—SageMaker Canvas also includes Amazon SageMaker Data Wrangler, which you can use to prepare, featurize, and analyze your data. This allows you to do additional transformations as you experiment and iterate. You should continue to run these small experiments while making changes to the training dataset with the goal of getting the best performance from your model, while reducing the training time and the latency in inference.

After experimenting, you will identify the most important features and how you want to transform your data. When you’re confident in your model’s performance, you can decide how to deploy the trained model.

Final model deployment and right-sizing

Once your model is trained, you will need to deploy an endpoint so that you can invoke your model and consume the results via API. For example, the diagram below shows a Lambda Function calling the deployed endpoint. We continue to use the DynamoDB table as a cache. This way we avoid reprocessing numbers.

Portion of the architecture focusing on SageMaker model invocation

SageMaker Canvas offers a default deployment option where you can choose the instance type and number of instances to host the trained model that will meet your scaling needs. To help ensure that these instances aren’t over- or under-provisioned, SageMaker provides multiple features to help you optimize your deployment to your specific needs.

  • Autoscaling: Autoscaling dynamically adjusts the number of instances provisioned for a model in response to workload changes. The steps to make this change are described in detail in Configure model autoscaling. SageMaker recently introduced Scale Down to Zero for AI inference, which allows endpoints to scale to zero instances during periods of inactivity and can help customers save costs.
  • Inference recommender: Amazon SageMaker Inference Recommender reduces the time required to get ML models into production by automating load testing and model tuning across SageMaker ML instances.
  • Serverless deployment: Amazon SageMaker Serverless Inference is a purpose-built inference option that you can use to deploy and scale ML models without configuring or managing any of the underlying infrastructure. Compute resources scale automatically depending on traffic, eliminating the need to choose instance types or manage scaling policies. To learn more, see Serverless endpoint operations.

To have use a serverless deployment and obtain inference recommendations, a single-container model is needed. This is currently not possible when using SageMaker Data Wrangler, because it generates two containers following data transformation: one for data preprocessing and one for model prediction.

After preparing the final dataset, you can bring it into SageMaker Canvas to train the detection model. Follow the same steps as you did with the smaller tests, making sure that you don’t use any of the data transformation options within SageMaker Canvas.

Depending on the size and complexity of the final dataset, the training process can take several hours to complete. After the training is complete, SageMaker Canvas will generate a trained model that you can immediately deploy to an endpoint.

Conclusion

By using the power of Amazon SageMaker Canvas, you can build, train, and deploy a robust fraud detection model, empowering your call center to deliver exceptional customer experiences while safeguarding your business and allowing your human agents to focus on legitimate customers.

You can begin testing SageMaker Canvas using the AWS Management Console today or learn more about SageMaker Canvas basics at the SageMaker Canvas Immersion Day workshop.


About the authors

Get insights from multimodal content with Amazon Bedrock Data Automation, now generally available

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/get-insights-from-multimodal-content-with-amazon-bedrock-data-automation-now-generally-available/

Many applications need to interact with content available through different modalities. Some of these applications process complex documents, such as insurance claims and medical bills. Mobile apps need to analyze user-generated media. Organizations need to build a semantic index on top of their digital assets that include documents, images, audio, and video files. However, getting insights from unstructured multimodal content is not easy to set up: you have to implement processing pipelines for the different data formats and go through multiple steps to get the information you need. That usually means having multiple models in production for which you have to handle cost optimizations (through fine-tuning and prompt engineering), safeguards (for example, against hallucinations), integrations with the target applications (including data formats), and model updates.

To make this process easier, we introduced in preview during AWS re:Invent Amazon Bedrock Data Automation, a capability of Amazon Bedrock that streamlines the generation of valuable insights from unstructured, multimodal content such as documents, images, audio, and videos. With Bedrock Data Automation, you can reduce the development time and effort to build intelligent document processing, media analysis, and other multimodal data-centric automation solutions.

You can use Bedrock Data Automation as a standalone feature or as a parser for Amazon Bedrock Knowledge Bases to index insights from multimodal content and provide more relevant responses for Retrieval-Augmented Generation (RAG).

Today, Bedrock Data Automation is now generally available with support for cross-region inference endpoints to be available in more AWS Regions and seamlessly use compute across different locations. Based on your feedback during the preview, we also improved accuracy and added support for logo recognition for images and videos.

Let’s have a look at how this works in practice.

Using Amazon Bedrock Data Automation with cross-region inference endpoints
The blog post published for the Bedrock Data Automation preview shows how to use the visual demo in the Amazon Bedrock console to extract information from documents and videos. I recommend you go through the console demo experience to understand how this capability works and what you can do to customize it. For this post, I focus more on how Bedrock Data Automation works in your applications, starting with a few steps in the console and following with code samples.

The Data Automation section of the Amazon Bedrock console now asks for confirmation to enable cross-region support the first time you access it. For example:

Console screenshot.

From an API perspective, the InvokeDataAutomationAsync operation now requires an additional parameter (dataAutomationProfileArn) to specify the data automation profile to use. The value for this parameter depends on the Region and your AWS account ID:

arn:aws:bedrock:<REGION>:<ACCOUNT_ID>:data-automation-profile/us.data-automation-v1

Also, the dataAutomationArn parameter has been renamed to dataAutomationProjectArn to better reflect that it contains the project Amazon Resource Name (ARN). When invoking Bedrock Data Automation, you now need to specify a project or a blueprint to use. If you pass in blueprints, you will get custom output. To continue to get standard default output, configure the parameter DataAutomationProjectArn to use arn:aws:bedrock:<REGION>:aws:data-automation-project/public-default.

As the name suggests, the InvokeDataAutomationAsync operation is asynchronous. You pass the input and output configuration and, when the result is ready, it’s written on an Amazon Simple Storage Service (Amazon S3) bucket as specified in the output configuration. You can receive an Amazon EventBridge notification from Bedrock Data Automation using the notificationConfiguration parameter.

With Bedrock Data Automation, you can configure outputs in two ways:

  • Standard output delivers predefined insights relevant to a data type, such as document semantics, video chapter summaries, and audio transcripts. With standard outputs, you can set up your desired insights in just a few steps.
  • Custom output lets you specify extraction needs using blueprints for more tailored insights.

To see the new capabilities in action, I create a project and customize the standard output settings. For documents, I choose plain text instead of markdown. Note that you can automate these configuration steps using the Bedrock Data Automation API.

Console screenshot.

For videos, I want a full audio transcript and a summary of the entire video. I also ask for a summary of each chapter.

Console screenshot.

To configure a blueprint, I choose Custom output setup in the Data automation section of the Amazon Bedrock console navigation pane. There, I search for the US-Driver-License sample blueprint. You can browse other sample blueprints for more examples and ideas.

Sample blueprints can’t be edited, so I use the Actions menu to duplicate the blueprint and add it to my project. There, I can fine-tune the data to be extracted by modifying the blueprint and adding custom fields that can use generative AI to extract or compute data in the format I need.

Console screenshot.

I upload the image of a US driver’s license on an S3 bucket. Then, I use this sample Python script that uses Bedrock Data Automation through the AWS SDK for Python (Boto3) to extract text information from the image:

import json
import sys
import time

import boto3

DEBUG = False

AWS_REGION = '<REGION>'
BUCKET_NAME = '<BUCKET>'
INPUT_PATH = 'BDA/Input'
OUTPUT_PATH = 'BDA/Output'

PROJECT_ID = '<PROJECT_ID>'
BLUEPRINT_NAME = 'US-Driver-License-demo'

# Fields to display
BLUEPRINT_FIELDS = [
    'NAME_DETAILS/FIRST_NAME',
    'NAME_DETAILS/MIDDLE_NAME',
    'NAME_DETAILS/LAST_NAME',
    'DATE_OF_BIRTH',
    'DATE_OF_ISSUE',
    'EXPIRATION_DATE'
]

# AWS SDK for Python (Boto3) clients
bda = boto3.client('bedrock-data-automation-runtime', region_name=AWS_REGION)
s3 = boto3.client('s3', region_name=AWS_REGION)
sts = boto3.client('sts')


def log(data):
    if DEBUG:
        if type(data) is dict:
            text = json.dumps(data, indent=4)
        else:
            text = str(data)
        print(text)

def get_aws_account_id() -> str:
    return sts.get_caller_identity().get('Account')


def get_json_object_from_s3_uri(s3_uri) -> dict:
    s3_uri_split = s3_uri.split('/')
    bucket = s3_uri_split[2]
    key = '/'.join(s3_uri_split[3:])
    object_content = s3.get_object(Bucket=bucket, Key=key)['Body'].read()
    return json.loads(object_content)


def invoke_data_automation(input_s3_uri, output_s3_uri, data_automation_arn, aws_account_id) -> dict:
    params = {
        'inputConfiguration': {
            's3Uri': input_s3_uri
        },
        'outputConfiguration': {
            's3Uri': output_s3_uri
        },
        'dataAutomationConfiguration': {
            'dataAutomationProjectArn': data_automation_arn
        },
        'dataAutomationProfileArn': f"arn:aws:bedrock:{AWS_REGION}:{aws_account_id}:data-automation-profile/us.data-automation-v1"
    }

    response = bda.invoke_data_automation_async(**params)
    log(response)

    return response

def wait_for_data_automation_to_complete(invocation_arn, loop_time_in_seconds=1) -> dict:
    while True:
        response = bda.get_data_automation_status(
            invocationArn=invocation_arn
        )
        status = response['status']
        if status not in ['Created', 'InProgress']:
            print(f" {status}")
            return response
        print(".", end='', flush=True)
        time.sleep(loop_time_in_seconds)


def print_document_results(standard_output_result):
    print(f"Number of pages: {standard_output_result['metadata']['number_of_pages']}")
    for page in standard_output_result['pages']:
        print(f"- Page {page['page_index']}")
        if 'text' in page['representation']:
            print(f"{page['representation']['text']}")
        if 'markdown' in page['representation']:
            print(f"{page['representation']['markdown']}")


def print_video_results(standard_output_result):
    print(f"Duration: {standard_output_result['metadata']['duration_millis']} ms")
    print(f"Summary: {standard_output_result['video']['summary']}")
    statistics = standard_output_result['statistics']
    print("Statistics:")
    print(f"- Speaket count: {statistics['speaker_count']}")
    print(f"- Chapter count: {statistics['chapter_count']}")
    print(f"- Shot count: {statistics['shot_count']}")
    for chapter in standard_output_result['chapters']:
        print(f"Chapter {chapter['chapter_index']} {chapter['start_timecode_smpte']}-{chapter['end_timecode_smpte']} ({chapter['duration_millis']} ms)")
        if 'summary' in chapter:
            print(f"- Chapter summary: {chapter['summary']}")


def print_custom_results(custom_output_result):
    matched_blueprint_name = custom_output_result['matched_blueprint']['name']
    log(custom_output_result)
    print('\n- Custom output')
    print(f"Matched blueprint: {matched_blueprint_name}  Confidence: {custom_output_result['matched_blueprint']['confidence']}")
    print(f"Document class: {custom_output_result['document_class']['type']}")
    if matched_blueprint_name == BLUEPRINT_NAME:
        print('\n- Fields')
        for field_with_group in BLUEPRINT_FIELDS:
            print_field(field_with_group, custom_output_result)


def print_results(job_metadata_s3_uri) -> None:
    job_metadata = get_json_object_from_s3_uri(job_metadata_s3_uri)
    log(job_metadata)

    for segment in job_metadata['output_metadata']:
        asset_id = segment['asset_id']
        print(f'\nAsset ID: {asset_id}')

        for segment_metadata in segment['segment_metadata']:
            # Standard output
            standard_output_path = segment_metadata['standard_output_path']
            standard_output_result = get_json_object_from_s3_uri(standard_output_path)
            log(standard_output_result)
            print('\n- Standard output')
            semantic_modality = standard_output_result['metadata']['semantic_modality']
            print(f"Semantic modality: {semantic_modality}")
            match semantic_modality:
                case 'DOCUMENT':
                    print_document_results(standard_output_result)
                case 'VIDEO':
                    print_video_results(standard_output_result)
            # Custom output
            if 'custom_output_status' in segment_metadata and segment_metadata['custom_output_status'] == 'MATCH':
                custom_output_path = segment_metadata['custom_output_path']
                custom_output_result = get_json_object_from_s3_uri(custom_output_path)
                print_custom_results(custom_output_result)


def print_field(field_with_group, custom_output_result) -> None:
    inference_result = custom_output_result['inference_result']
    explainability_info = custom_output_result['explainability_info'][0]
    if '/' in field_with_group:
        # For fields part of a group
        (group, field) = field_with_group.split('/')
        inference_result = inference_result[group]
        explainability_info = explainability_info[group]
    else:
        field = field_with_group
    value = inference_result[field]
    confidence = explainability_info[field]['confidence']
    print(f'{field}: {value or '<EMPTY>'}  Confidence: {confidence}')


def main() -> None:
    if len(sys.argv) < 2:
        print("Please provide a filename as command line argument")
        sys.exit(1)
      
    file_name = sys.argv[1]
    
    aws_account_id = get_aws_account_id()
    input_s3_uri = f"s3://{BUCKET_NAME}/{INPUT_PATH}/{file_name}" # File
    output_s3_uri = f"s3://{BUCKET_NAME}/{OUTPUT_PATH}" # Folder
    data_automation_arn = f"arn:aws:bedrock:{AWS_REGION}:{aws_account_id}:data-automation-project/{PROJECT_ID}"

    print(f"Invoking Bedrock Data Automation for '{file_name}'", end='', flush=True)

    data_automation_response = invoke_data_automation(input_s3_uri, output_s3_uri, data_automation_arn, aws_account_id)
    data_automation_status = wait_for_data_automation_to_complete(data_automation_response['invocationArn'])

    if data_automation_status['status'] == 'Success':
        job_metadata_s3_uri = data_automation_status['outputConfiguration']['s3Uri']
        print_results(job_metadata_s3_uri)


if __name__ == "__main__":
    main()

The initial configuration in the script includes the name of the S3 bucket to use in input and output, the location of the input file in the bucket, the output path for the results, the project ID to use to get custom output from Bedrock Data Automation, and the blueprint fields to show in output.

I run the script passing the name of the input file. In output, I see the information extracted by Bedrock Data Automation. The US-Driver-License is a match and the name and dates in the driver’s license are printed in output.

python bda-ga.py bda-drivers-license.jpeg

Invoking Bedrock Data Automation for 'bda-drivers-license.jpeg'................ Success

Asset ID: 0

- Standard output
Semantic modality: DOCUMENT
Number of pages: 1
- Page 0
NEW JERSEY

Motor Vehicle
 Commission

AUTO DRIVER LICENSE

Could DL M6454 64774 51685                      CLASS D
        DOB 01-01-1968
ISS 03-19-2019          EXP     01-01-2023
        MONTOYA RENEE MARIA 321 GOTHAM AVENUE TRENTON, NJ 08666 OF
        END NONE
        RESTR NONE
        SEX F HGT 5'-08" EYES HZL               ORGAN DONOR
        CM ST201907800000019 CHG                11.00

[SIGNATURE]


- Custom output
Matched blueprint: US-Driver-License-copy  Confidence: 1
Document class: US-drivers-licenses

- Fields
FIRST_NAME: RENEE  Confidence: 0.859375
MIDDLE_NAME: MARIA  Confidence: 0.83203125
LAST_NAME: MONTOYA  Confidence: 0.875
DATE_OF_BIRTH: 1968-01-01  Confidence: 0.890625
DATE_OF_ISSUE: 2019-03-19  Confidence: 0.79296875
EXPIRATION_DATE: 2023-01-01  Confidence: 0.93359375

As expected, I see in output the information I selected from the blueprint associated with the Bedrock Data Automation project.

Similarly, I run the same script on a video file from my colleague Mike Chambers. To keep the output small, I don’t print the full audio transcript or the text displayed in the video.

python bda.py mike-video.mp4
Invoking Bedrock Data Automation for 'mike-video.mp4'.......................................................................................................................................................................................................................................................................... Success

Asset ID: 0

- Standard output
Semantic modality: VIDEO
Duration: 810476 ms
Summary: In this comprehensive demonstration, a technical expert explores the capabilities and limitations of Large Language Models (LLMs) while showcasing a practical application using AWS services. He begins by addressing a common misconception about LLMs, explaining that while they possess general world knowledge from their training data, they lack current, real-time information unless connected to external data sources.

To illustrate this concept, he demonstrates an "Outfit Planner" application that provides clothing recommendations based on location and weather conditions. Using Brisbane, Australia as an example, the application combines LLM capabilities with real-time weather data to suggest appropriate attire like lightweight linen shirts, shorts, and hats for the tropical climate.

The demonstration then shifts to the Amazon Bedrock platform, which enables users to build and scale generative AI applications using foundation models. The speaker showcases the "OutfitAssistantAgent," explaining how it accesses real-time weather data to make informed clothing recommendations. Through the platform's "Show Trace" feature, he reveals the agent's decision-making process and how it retrieves and processes location and weather information.

The technical implementation details are explored as the speaker configures the OutfitAssistant using Amazon Bedrock. The agent's workflow is designed to be fully serverless and managed within the Amazon Bedrock service.

Further diving into the technical aspects, the presentation covers the AWS Lambda console integration, showing how to create action group functions that connect to external services like the OpenWeatherMap API. The speaker emphasizes that LLMs become truly useful when connected to tools providing relevant data sources, whether databases, text files, or external APIs.

The presentation concludes with the speaker encouraging viewers to explore more AWS developer content and engage with the channel through likes and subscriptions, reinforcing the practical value of combining LLMs with external data sources for creating powerful, context-aware applications.
Statistics:
- Speaket count: 1
- Chapter count: 6
- Shot count: 48
Chapter 0 00:00:00:00-00:01:32:01 (92025 ms)
- Chapter summary: A man with a beard and glasses, wearing a gray hooded sweatshirt with various logos and text, is sitting at a desk in front of a colorful background. He discusses the frequent release of new large language models (LLMs) and how people often test these models by asking questions like "Who won the World Series?" The man explains that LLMs are trained on general data from the internet, so they may have information about past events but not current ones. He then poses the question of what he wants from an LLM, stating that he desires general world knowledge, such as understanding basic concepts like "up is up" and "down is down," but does not need specific factual knowledge. The man suggests that he can attach other systems to the LLM to access current factual data relevant to his needs. He emphasizes the importance of having general world knowledge and the ability to use tools and be linked into agentic workflows, which he refers to as "agentic workflows." The man encourages the audience to add this term to their spell checkers, as it will likely become commonly used.
Chapter 1 00:01:32:01-00:03:38:18 (126560 ms)
- Chapter summary: The video showcases a man with a beard and glasses demonstrating an "Outfit Planner" application on his laptop. The application allows users to input their location, such as Brisbane, Australia, and receive recommendations for appropriate outfits based on the weather conditions. The man explains that the application generates these recommendations using large language models, which can sometimes provide inaccurate or hallucinated information since they lack direct access to real-world data sources.

The man walks through the process of using the Outfit Planner, entering Brisbane as the location and receiving weather details like temperature, humidity, and cloud cover. He then shows how the application suggests outfit options, including a lightweight linen shirt, shorts, sandals, and a hat, along with an image of a woman wearing a similar outfit in a tropical setting.

Throughout the demonstration, the man points out the limitations of current language models in providing accurate and up-to-date information without external data connections. He also highlights the need to edit prompts and adjust settings within the application to refine the output and improve the accuracy of the generated recommendations.
Chapter 2 00:03:38:18-00:07:19:06 (220620 ms)
- Chapter summary: The video demonstrates the Amazon Bedrock platform, which allows users to build and scale generative AI applications using foundation models (FMs). [speaker_0] introduces the platform's overview, highlighting its key features like managing FMs from AWS, integrating with custom models, and providing access to leading AI startups. The video showcases the Amazon Bedrock console interface, where [speaker_0] navigates to the "Agents" section and selects the "OutfitAssistantAgent" agent. [speaker_0] tests the OutfitAssistantAgent by asking it for outfit recommendations in Brisbane, Australia. The agent provides a suggestion of wearing a light jacket or sweater due to cool, misty weather conditions. To verify the accuracy of the recommendation, [speaker_0] clicks on the "Show Trace" button, which reveals the agent's workflow and the steps it took to retrieve the current location details and weather information for Brisbane. The video explains that the agent uses an orchestration and knowledge base system to determine the appropriate response based on the user's query and the retrieved data. It highlights the agent's ability to access real-time information like location and weather data, which is crucial for generating accurate and relevant responses.
Chapter 3 00:07:19:06-00:11:26:13 (247214 ms)
- Chapter summary: The video demonstrates the process of configuring an AI assistant agent called "OutfitAssistant" using Amazon Bedrock. [speaker_0] introduces the agent's purpose, which is to provide outfit recommendations based on the current time and weather conditions. The configuration interface allows selecting a language model from Anthropic, in this case the Claud 3 Haiku model, and defining natural language instructions for the agent's behavior. [speaker_0] explains that action groups are groups of tools or actions that will interact with the outside world. The OutfitAssistant agent uses Lambda functions as its tools, making it fully serverless and managed within the Amazon Bedrock service. [speaker_0] defines two action groups: "get coordinates" to retrieve latitude and longitude coordinates from a place name, and "get current time" to determine the current time based on the location. The "get current weather" action requires calling the "get coordinates" action first to obtain the location coordinates, then using those coordinates to retrieve the current weather information. This demonstrates the agent's workflow and how it utilizes the defined actions to generate outfit recommendations. Throughout the video, [speaker_0] provides details on the agent's configuration, including its name, description, model selection, instructions, and action groups. The interface displays various options and settings related to these aspects, allowing [speaker_0] to customize the agent's behavior and functionality.
Chapter 4 00:11:26:13-00:13:00:17 (94160 ms)
- Chapter summary: The video showcases a presentation by [speaker_0] on the AWS Lambda console and its integration with machine learning models for building powerful agents. [speaker_0] demonstrates how to create an action group function using AWS Lambda, which can be used to generate text responses based on input parameters like location, time, and weather data. The Lambda function code is shown, utilizing external services like OpenWeatherMap API for fetching weather information. [speaker_0] explains that for a large language model to be useful, it needs to connect to tools providing relevant data sources, such as databases, text files, or external APIs. The presentation covers the process of defining actions, setting up Lambda functions, and leveraging various tools within the AWS environment to build intelligent agents capable of generating context-aware responses.
Chapter 5 00:13:00:17-00:13:28:10 (27761 ms)
- Chapter summary: A man with a beard and glasses, wearing a gray hoodie with various logos and text, is sitting at a desk in front of a colorful background. He is using a laptop computer that has stickers and logos on it, including the AWS logo. The man appears to be presenting or speaking about AWS (Amazon Web Services) and its services, such as Lambda functions and large language models. He mentions that if a Lambda function can do something, then it can be used to augment a large language model. The man concludes by expressing hope that the viewer found the video useful and insightful, and encourages them to check out other videos on the AWS developers channel. He also asks viewers to like the video, subscribe to the channel, and watch other videos.

Things to know
Amazon Bedrock Data Automation is now available via cross-region inference in the following two AWS Regions: US East (N. Virginia) and US West (Oregon). When using Bedrock Data Automation from those Regions, data can be processed using cross-region inference in any of these four Regions: US East (Ohio, N. Virginia) and US West (N. California, Oregon). All these Regions are in the US so that data is processed within the same geography. We’re working to add support for more Regions in Europe and Asia later in 2025.

There’s no change in pricing compared to the preview and when using cross-region inference. For more information, visit Amazon Bedrock pricing.

Bedrock Data Automation now also includes a number of security, governance and manageability related capabilities such as AWS Key Management Service (AWS KMS) customer managed keys support for granular encryption control, AWS PrivateLink to connect directly to the Bedrock Data Automation APIs in your virtual private cloud (VPC) instead of connecting over the internet, and tagging of Bedrock Data Automation resources and jobs to track costs and enforce tag-based access policies in AWS Identity and Access Management (IAM).

I used Python in this blog post but Bedrock Data Automation is available with any AWS SDKs. For example, you can use Java, .NET, or Rust for a backend document processing application; JavaScript for a web app that processes images, videos, or audio files; and Swift for a native mobile app that processes content provided by end users. It’s never been so easy to get insights from multimodal data.

Here are a few reading suggestions to learn more (including code samples):

Danilo

How is the News Blog doing? Take this 1 minute survey!

AWS Weekly Roundup: Anthropic Claude 3.7, JAWS Days, cross-account access, and more (March 3, 2025)

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-anthropic-claude-3-7-jaws-days-cross-account-access-and-more-march-3-2025/

I have fond memories of the time I built an application live at the AWS GenAI Loft London last September. AWS GenAI Lofts are back in locations such as San Francisco, Berlin, and more, to continue providing collaborative spaces and immersive experiences for startups and developers. Find a loft near you for hands-on access to AI products and services, events, workshops, and networking opportunities, that you can’t miss!

Last week’s launches
Here are some launches that got my attention during the previous week.

Four ways to grant cross-account access in AWS — For some situations, you might want to enable centralized operations across multiple AWS accounts or share resources across teams, or projects within your teams. In these cases, you may be concerned about security, availability, or the manageability of granting this cross-account access. We’ve announced four ways to grant cross-account access in AWS and detail each of the methods and its unique trade-offs.

Amazon ECS adds support for additional IAM condition keys — We’ve launched eight new service-specific condition keys for Identity and Access Management (IAM). These new condition keys let you create IAM policies as well as srvice control policies (SCPs) to better enforce your organizational policies in containerized environments. You can use IAM condition keys to author policies that enforce access control based on API request context.

AWS Chatbot is now named Amazon Q Developer — AWS Chatbot has been renamed to Amazon Q Developer, representing an enhancement to developer productivity through generative AI-powered capabilities. Furthermore, this update is an enhancement of our chat-based DevOps capabilities. By combining the proven functionality of AWS Chatbot with the generative AI capabilities of Amazon Q, we’re providing developers with more intuitive, efficient tools for cloud resource management.

Anthropic’s Claude 3.7 Sonnet hybrid reasoning model is now available in Amazon Bedrock — We’re expanding the foundation models (FM) offerings of Amazon Bedrock and we’ve announced the availability of Anthropic’s Claude 3.7 Sonnet FM in Amazon Bedrock. Claude 3.7 Sonnet is Anthropic’s most intelligent model to date. It stands out as their first hybrid reasoning model capable of producing quick responses or extended thinking, meaning it can work through difficult problems using careful, step-by-step reasoning.

Other AWS news
JAWS-UG (Japan AWS User Group) is the largest AWS user group in the world, and holds JAWS Days every year with over a thousand participants from Japan, Korea, Taiwan, and Hong Kong. The March 1st event started with a keynote speech on next-generation development by Jeff Barr (VP of AWS Evangelism), and included over 100 technical and community experience sessions, lightning talks, and workshops such as Game Days, Builders Card Challenges, and networking parties. If you want to experience the most active AWS community event in the world, I recommend attending next year.


Amazon Q Developer now generally available in Amazon SageMaker Canvas — Announced as available in preview at AWS reinvent 2024, Amazon Q Developer is now generally available in Amazon SageMaker Canvas to help you build machine learning (ML) models using natural language.

Applications for the 2025 AWS Cloud Club Captains Program are still open through March 6th. AWS Cloud Clubs are student-led groups for post-secondary and independent students, 18 years old and over. Find a club near you on the Meetup page.

From community.aws
Here are some of my favorite posts from community.aws:

DevSecOps on AWS: Secure, Automate, and Have a Laugh Along the Way – Discover how DevSecOps on AWS transforms your development pipeline by integrating security from the very first commit to production deployment, by Ahmed Mohamed.

Find out how to earn 100 percent free AWS certification vouchers in Opportunity to earn free AWS Certification Vouchers, published by Anand Joshi.

In the post, Boost SaaS Onboarding & Retention with AWS AI & Automation, Kaumudi Tiwari details how to navigate endless forms, generic guides, and a cluttered interface when signing up for a new software as a service (SaaS) platform.

My colleague Dennis Traub has published helpful step-by-step guides on how to use reasoning capabilities with Anthropic’s Claude 3.7 Sonnet in your C#/.NET, Java, JavaScript, or Python applications. Find these posts and much more generative AI-related content in the Gen AI Space on community.aws.

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events:

AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Milan, Italy (April 2), Bay Area – Security Edition (April 4), Timișoara, Romania (April 10), and Prague, Czech Republic (April 29).

AWS Innovate: Generative AI + Data – Join a free online conference focusing on generative AI and data innovations. Available in multiple geographic regions: APJC and EMEA (March 6), North America (March 13), Greater China Region (March 14), and Latin America (April 8).

AWS Summits – Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Paris (April 9), Amsterdam (April 16), London (April 30), and Poland (May 5).

AWS re:Inforce – AWS re:Inforce (June 16–18) in Philadelphia, PA, is our annual learning event devoted to all things AWS Cloud security. Registration opens in March, so be ready to join more than 5,000 security builders and leaders.

AWS DevDays are free, technical events where developers can learn about some of the hottest topics in cloud computing. DevDays offer hands-on workshops, technical sessions, live demos, and networking with AWS technical experts and your peers. Register to access AWS DevDays sessions on demand.

Create your AWS Builder ID and reserve your alias. Builder ID is a universal login credential that gives you access—beyond the AWS Management Console—to AWS tools and resources, including over 600 free training courses, community features, and developer tools such as Amazon Q Developer.

AWS Training and Certification hosts free training events, both online and in-person, that help you get the most out of the AWS Cloud. Register to gain foundational cloud knowledge or dive deep in a technical area. Join AWS experts for training events that meet your goals, such as AWS Discovery Days, in-person. and virtual events at AWS Skills Centers including the one in Cape Town.

You can browse all upcoming in-person and virtual events here.

That’s all for this week. Check back next Monday for another Weekly Roundup!

– Veliswa

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

How is the News Blog doing? Take this 1 minute survey!

Use generative AI on AWS for efficient clinical document analysis

Post Syndicated from Alex Boudreau original https://aws.amazon.com/blogs/architecture/use-generative-ai-on-aws-for-efficient-clinical-document-analysis/

Clinical trials involve the ingestion and processing of vast amounts of highly regulated data, including complex protocol documents that describe how the trial will be conducted. Managing this volume of information can be overwhelming, but generative AI offers a solution by helping automate the process and enabling clinical researchers to quickly focus on the most relevant information. Currently, the drug approval process takes on average 10–12 years, with clinical trial study startup time accounting for 1 year of that timeframe. Much of the challenge with study startup lies in the complex and non-standard nature of protocol documents. These often require weeks or months of effort to review and assess. This review time adds to the already long cycle time to bring a new drug to market.

In this post, we show how Clario uses the AWS platform to accelerate clinical document analysis.

About Clario

Clario is a leading provider of endpoint data solutions to the clinical trials industry providing regulatory-grade clinical evidence for pharmaceutical, biotech, and medical device partners. Since Clario’s founding more than 50 years ago, their endpoint data solutions have supported clinical trials more than 26,000 times with over 700 regulatory approvals across more than 100 countries. One of the critical challenges Clario faces is the time-consuming process of generating documentation for clinical trials, which can take weeks or months.

The business challenge

Clinical trials are essential for the approval of new health innovations, including treatments, procedures, and medical devices. They require the collection of vast quantities of complex data from dispersed clinical trial sites to support assessments of medical benefits and risks, all while maintaining privacy and regulatory compliance. To make matters even more challenging, capturing data in clinical trial occurs not only in healthcare centers but also through remote capture through various aspects of trial participants’ daily activities.

Partners like Clario understand the challenges faced by life sciences companies when it comes to analyzing large volumes of complex clinical documents, such as study protocols. These documents often contain a mix of structured and unstructured data, including tables, images, and diagrams, making it difficult to accurately interpret and extract key information at scale. In this post, we explore how Clario has used the power of generative AI on AWS to efficiently analyze clinical documents and drive better outcomes for its clients.

Harnessing the power of large language models

The rapid progress in large language models (LLMs) has expanded the potential applications of natural language processing beyond simple conversational AI assistants. Clario has experimented with various techniques, such as zero-shot learning, few-shot learning, classification, entity extraction, and summarization, for the effective use of LLMs in specialized use cases. By employing prompt engineering, AI orchestration, and content retrieval, Clario can guide the models to accurately generate insights and extract relevant information from key clinical research documents, including complex clinical trial protocols.

Four pillars of effective document analysis on AWS

Through its research and development efforts, Clario has identified four core pillars that enable effective document analysis using generative AI on AWS:

  • Parsing – Clario uses AWS services such as Amazon Textract and Amazon Comprehend to extract text, images, and tables from clinical documents, maintaining both data privacy and security.
  • Retrieval – By using embedding models and vector databases like Amazon OpenSearch Service, Clario efficiently stores and retrieves relevant information from large document collections based on similarity search. The team has experimented with various chunking and retrieval strategies to optimize accuracy and performance.
  • Prompting – Using techniques like zero-shot and few-shot learning, Clario has enhanced the accuracy of LLMs for classifying and extracting information . AWS services such as and Amazon Bedrock simplify experimentation with different prompting strategies and the evaluation of model performance.
  • Generation – Clario carefully considers factors such as context size, reasoning capabilities, and latency when selecting the appropriate LLMs for generating structured outputs. AWS offers a range of pre-trained models and frameworks that seamlessly integrate into Clario’s pipeline.

Solution overview

To tackle the unique challenges associated with analyzing clinical documents, Clario has built a custom generative AI platform on AWS. This platform incorporates an orchestration engine that combines multiple LLMs and deep learning models, enabling it to extract key information accurately and at scale. By using AWS services such as Amazon Elastic Compute Cloud (Amazon EC2), Amazon Elastic Kubernetes Service (Amazon EKS), Amazon Simple Storage Service (Amazon S3), SageMaker, and AWS Lambda, Clario can efficiently process thousands of documents in a matter of seconds.

The following diagram illustrates the solution architecture.

Solution Overview

The workflow consists of the following steps:

  • Documents are collected on premises (1) and uploaded using AWS Direct Connect (2) with encryption in transit to Amazon S3 (3). All uploaded documents are then automatically and securely stored with server-side object-level encryption.
  • After the documents are uploaded and the user has reviewed them, the Clario AI Orchestration Engine (4) determines the best document parsing strategy based on file type, and extracts text using Amazon Textract (5). Once extracted, the text is vectorized and stored in the Amazon OpenSearch Service vector engine (6) for later semantic retrieval.
  • After vectorization, the Clario AI Orchestration Engine (4), which runs as a distributed service in Amazon EKS, launches a document classification async task using Amazon MQ. Amazon EC2 and Lambda are used for additional processing if needed. This triggers the Document Classification Agent, which uses Amazon Bedrock LLMs (8), for automatically determining the document type.
  • After the documents are classified, the Clario AI Orchestration Engine (4) launches the appropriate document analysis agent for further background processing. In the case of study protocols, the engine launches the Protocol Analysis agent, which uses a predefined analysis graph configuration stored in Amazon Relational Database Service (Amazon RDS) (7), as well as a combination of retrieval strategies and AI models, including custom deep learning models on SageMaker (9), and pre-trained LLMs on Amazon Bedrock (8). This orchestration powers advanced document analysis, transforming massive amounts of unstructured multi-modal data into structured data and insights.
  • Following the analysis, all structured data is then persisted to Amazon RDS (7) for later visualization, review, and querying.

Recommendations and best practices

Based on their experience developing and deploying generative AI solutions on AWS, Clario learned the following best practices:

  • Adopt an incremental and iterative development approach to gradually build and refine your models
  • Follow a standard machine learning approach for evaluating and validating model performance using representative test sets
  • Optimize the four pillars of document analysis before investing in fine-tuning and continuous pre-training of LLMs
  • Tailor your approaches to specific use cases, because not all problems require the same models or techniques

Conclusion

By using the power of generative AI on AWS, Clario has been able to efficiently analyze complex clinical trial documents and extract valuable insights for its clients in the life sciences industry. Through a combination of careful model selection, iterative development, and adherence to best practices, Clario has built a scalable and accurate document analysis pipeline using AWS. Unlock the full potential of your clinical trial data by applying these best practices with an AWS generative AI solution today.


About the Authors

DeepSeek-R1 models now available on AWS

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/deepseek-r1-models-now-available-on-aws/

During this past AWS re:Invent, Amazon CEO Andy Jassy shared valuable lessons learned from Amazon’s own experience developing nearly 1,000 generative AI applications across the company. Drawing from this extensive scale of AI deployment, Jassy offered three key observations that have shaped Amazon’s approach to enterprise AI implementation.

First is that as you get to scale in generative AI applications, the cost of compute really matters. People are very hungry for better price performance. The second is actually quite difficult to build a really good generative AI application. The third is the diversity of the models being used when we gave our builders freedom to pick what they want to do. It doesn’t surprise us, because we keep learning the same lesson over and over and over again, which is that there is never going to be one tool to rule the world.

As Andy emphasized, a broad and deep range of models provided by Amazon empowers customers to choose the precise capabilities that best serve their unique needs. By closely monitoring both customer needs and technological advancements, AWS regularly expands our curated selection of models to include promising new models alongside established industry favorites. This ongoing expansion of high-performing and differentiated model offerings helps customers stay at the forefront of AI innovation.

This leads us to Chinese AI startup DeepSeek. DeepSeek launched DeepSeek-V3 on December 2024 and subsequently released DeepSeek-R1, DeepSeek-R1-Zero with 671 billion parameters, and DeepSeek-R1-Distill models ranging from 1.5–70 billion parameters on January 20, 2025. They added their vision-based Janus-Pro-7B model on January 27, 2025. The models are publicly available and are reportedly 90-95% more affordable and cost-effective than comparable models. Per Deepseek, their model stands out for its reasoning capabilities, achieved through innovative training techniques such as reinforcement learning.

Today, you can now deploy DeepSeek-R1 models in Amazon Bedrock and Amazon SageMaker AI. Amazon Bedrock is best for teams seeking to quickly integrate pre-trained foundation models through APIs. Amazon SageMaker AI is ideal for organizations that want advanced customization, training, and deployment, with access to the underlying infrastructure. Additionally, you can also use AWS Trainium and AWS Inferentia to deploy DeepSeek-R1-Distill models cost-effectively via Amazon Elastic Compute Cloud (Amazon EC2) or Amazon SageMaker AI.

With AWS, you can use DeepSeek-R1 models to build, experiment, and responsibly scale your generative AI ideas by using this powerful, cost-efficient model with minimal infrastructure investment. You can also confidently drive generative AI innovation by building on AWS services that are uniquely designed for security. We highly recommend integrating your deployments of the DeepSeek-R1 models with Amazon Bedrock Guardrails to add a layer of protection for your generative AI applications, which can be used by both Amazon Bedrock and Amazon SageMaker AI customers.

You can choose how to deploy DeepSeek-R1 models on AWS today in a few ways: 1/ Amazon Bedrock Marketplace for the DeepSeek-R1 model, 2/ Amazon SageMaker JumpStart for the DeepSeek-R1 model, 3/ Amazon Bedrock Custom Model Import for the DeepSeek-R1-Distill models, and 4/ Amazon EC2 Trn1 instances for the DeepSeek-R1-Distill models.

Let me walk you through the various paths for getting started with DeepSeek-R1 models on AWS. Whether you’re building your first AI application or scaling existing solutions, these methods provide flexible starting points based on your team’s expertise and requirements.

1. The DeepSeek-R1 model in Amazon Bedrock Marketplace
Amazon Bedrock Marketplace offers over 100 popular, emerging, and specialized FMs alongside the current selection of industry-leading models in Amazon Bedrock. You can easily discover models in a single catalog, subscribe to the model, and then deploy the model on managed endpoints.

To access the DeepSeek-R1 model in Amazon Bedrock Marketplace, go to the Amazon Bedrock console and select Model catalog under the Foundation models section. You can quickly find DeepSeek by searching or filtering by model providers.

After checking out the model detail page including the model’s capabilities, and implementation guidelines, you can directly deploy the model by providing an endpoint name, choosing the number of instances, and selecting an instance type.

You can also configure advanced options that let you customize the security and infrastructure settings for the DeepSeek-R1 model including VPC networking, service role permissions, and encryption settings. For production deployments, you should review these settings to align with your organization’s security and compliance requirements.

With Amazon Bedrock Guardrails, you can independently evaluate user inputs and model outputs. You can control the interaction between users and DeepSeek-R1 with your defined set of policies by filtering undesirable and harmful content in generative AI applications. The DeepSeek-R1 model in Amazon Bedrock Marketplace can only be used with Bedrock’s ApplyGuardrail API to evaluate user inputs and model responses for custom and third-party FMs available outside of Amazon Bedrock. To learn more, read Implement model-independent safety measures with Amazon Bedrock Guardrails.

Amazon Bedrock Guardrails can also be integrated with other Bedrock tools including Amazon Bedrock Agents and Amazon Bedrock Knowledge Bases to build safer and more secure generative AI applications aligned with responsible AI policies. To learn more, visit the AWS Responsible AI page.

Refer to this step-by-step guide on how to deploy the DeepSeek-R1 model in Amazon Bedrock Marketplace. To learn more, visit Deploy models in Amazon Bedrock Marketplace.

2. The DeepSeek-R1 model in Amazon SageMaker JumpStart
Amazon SageMaker JumpStart is a machine learning (ML) hub with FMs, built-in algorithms, and prebuilt ML solutions that you can deploy with just a few clicks. To deploy DeepSeek-R1 in SageMaker JumpStart, you can discover the DeepSeek-R1 model in SageMaker Unified Studio, SageMaker Studio, SageMaker AI console, or programmatically through the SageMaker Python SDK.

In the Amazon SageMaker AI console, open SageMaker Unified Studio or SageMaker Studio. In case of SageMaker Studio, choose JumpStart and search for “DeepSeek-R1” in the All public models page.

You can select the model and choose deploy to create an endpoint with default settings. When the endpoint comes InService, you can make inferences by sending requests to its endpoint.

You can derive model performance and ML operations controls with Amazon SageMaker AI features such as Amazon SageMaker Pipelines, Amazon SageMaker Debugger, or container logs. The model is deployed in an AWS secure environment and under your virtual private cloud (VPC) controls, helping to support data security.

As like Bedrock Marketpalce, you can use the ApplyGuardrail API in the SageMaker JumpStart to decouple safeguards for your generative AI applications from the DeepSeek-R1 model. You can now use guardrails without invoking FMs, which opens the door to more integration of standardized and thoroughly tested enterprise safeguards to your application flow regardless of the models used.

Refer to this step-by-step guide on how to deploy DeepSeek-R1 in Amazon SageMaker JumpStart. To learn more, visit Discover SageMaker JumpStart models in SageMaker Unified Studio or Deploy SageMaker JumpStart models in SageMaker Studio.

3. DeepSeek-R1-Distill models using Amazon Bedrock Custom Model Import
Amazon Bedrock Custom Model Import provides the ability to import and use your customized models alongside existing FMs through a single serverless, unified API without the need to manage underlying infrastructure. With Amazon Bedrock Custom Model Import, you can import DeepSeek-R1-Distill Llama models ranging from 1.5–70 billion parameters. As I highlighted in my blog post about Amazon Bedrock Model Distillation, the distillation process involves training smaller, more efficient models to mimic the behavior and reasoning patterns of the larger DeepSeek-R1 model with 671 billion parameters by using it as a teacher model.

After storing these publicly available models in an Amazon Simple Storage Service (Amazon S3) bucket or an Amazon SageMaker Model Registry, go to Imported models under Foundation models in the Amazon Bedrock console and import and deploy them in a fully managed and serverless environment through Amazon Bedrock. This serverless approach eliminates the need for infrastructure management while providing enterprise-grade security and scalability.

Refer to this step-by-step guide on how to deploy DeepSeek-R1 models using Amazon Bedrock Custom Model Import. To learn more, visit Import a customized model into Amazon Bedrock.

4. DeepSeek-R1-Distill models using AWS Trainium and AWS Inferentia
AWS Deep Learning AMIs (DLAMI) provides customized machine images that you can use for deep learning in a variety of Amazon EC2 instances, from a small CPU-only instance to the latest high-powered multi-GPU instances. You can deploy the DeepSeek-R1-Distill models on AWS Trainuim1 or AWS Inferentia2 instances to get the best price-performance.

To get started, go to Amazon EC2 console and launch a trn1.32xlarge EC2 instance with the Neuron Multi Framework DLAMI called Deep Learning AMI Neuron (Ubuntu 22.04).

Once you have connected to your launched ec2 instance, install vLLM, an open-source tool to serve Large Language Models (LLMs) and download the DeepSeek-R1-Distill model from Hugging Face. You can deploy the model using vLLM and invoke the model server.

To learn more, refer to this step-by-step guide on how to deploy DeepSeek-R1-Distill Llama models on AWS Inferentia and Trainium.

You can also visit the DeepSeek-R1-Distill-Llama-8B or deepseek-ai/DeepSeek-R1-Distill-Llama-70B model cards on Hugging Face. Choose Deploy and then Amazon SageMaker. From the AWS Inferentia and Trainium tab, copy the example code for deploy DeepSeek-R1-Distill Llama models.

Since the release of DeepSeek-R1, various guides of its deployment for Amazon EC2 and Amazon Elastic Kubernetes Service (Amazon EKS) have been posted. Here is some additional material for you to check out:

Things to know
Here are a few important things to know.

  • Pricing – For publicly available models like DeepSeek-R1, you are charged only the infrastructure price based on inference instance hours you select for Amazon Bedrock Markeplace, Amazon SageMaker JumpStart, and Amazon EC2. For the Bedrock Custom Model Import, you are only charged for model inference, based on the number of copies of your custom model is active, billed in 5-minute windows. To learn more, check out the Amazon Bedrock Pricing, Amazon SageMaker AI Pricing, and Amazon EC2 Pricing pages.
  • Data security – You can use enterprise-grade security features in Amazon Bedrock and Amazon SageMaker to help you make your data and applications secure and private. This means your data is not shared with model providers, and is not used to improve the models. This applies to all models—proprietary and publicly available—like DeepSeek-R1 models on Amazon Bedrock and Amazon SageMaker. To learn more, visit Amazon Bedrock Security and Privacy and Security in Amazon SageMaker AI.

Now available
DeepSeek-R1 is generally available today in Amazon Bedrock Marketplace and Amazon SageMaker JumpStart. You can also use DeepSeek-R1-Distill models using Amazon Bedrock Custom Model Import and Amazon EC2 instances with AWS Trainum and Inferentia chips.

Give DeepSeek-R1 models a try today in the Amazon Bedrock console, Amazon SageMaker AI console, and Amazon EC2 console, and send feedback to AWS re:Post for Amazon Bedrock and AWS re:Post for SageMaker AI or through your usual AWS Support contacts.

Channy

Top Architecture Blog Posts of 2024

Post Syndicated from Andrea Courtright original https://aws.amazon.com/blogs/architecture/top-architecture-blog-posts-of-2024/

Well, it’s been another historic year! We’ve watched in awe as the use of real-world generative AI has changed the tech landscape, and while we at the Architecture Blog happily participated, we also made every effort to stay true to our channel’s original scope, and your readership this last year has proven that decision was the right one.

AI/ML carries itself in the top posts this year, but we’re also happy to see that foundational topics like resiliency and cost optimization are still of great interest to our audience.

(By the way, if you were hoping for more AI/ML content, head on over to our sister channel, the AWS Machine Learning Blog!).

Without further ado, here are our top posts from 2024!

#10 Deploy Stable Diffusion ComfyUI on AWS elastically and efficiently

This post helps you get started using ComfyUI, and was so successful that we followed it up later in the year with How to build custom nodes workflow with ComfyUI on EKS!

Architecture for deploying stable diffusion on ComfyUI

Figure 1. Architecture for deploying stable diffusion on ComfyUI

#9 Let’s Architect! Designing Well-Architected systems

In keeping with Let’s Architect! series, we have our first of three favorites for the year. This set of resources helps you apply Well-Architected standards in practice.

Let's Architect

Figure 2. Let’s Architect

#8 Let’s Architect! Learn About Machine Learning on AWS

As I said, Let’s Architect! has a winning series, and they’ve got a finger on the pulse of the tech world. This post about machine learning showcases some of the most exciting things happening at AWS.

Let's Architect

Figure 3. Let’s Architect

If you’re more interested in generative AI, you can also take a look at another post from 2024: Let’s Architect! GenAI

#7 Creating an organizational multi-Region failover strategy

Preparedness is another common theme in this year’s favorites. Michael, John, and Saurabh are well-versed in multi-Region architecture, and they’re here to share some strategies to contain failure impact.

When the application experiences an impairment using S3 resources in the primary Region, it fails over to use an S3 bucket in the secondary Region.

Figure 4. When the application experiences an impairment using S3 resources in the primary Region, it fails over to use an S3 bucket in the secondary Region.

#6 Building a three-tier architecture on a budget

Let’s talk cost optimization. This post about a three-tier architecture that relies on the AWS Free Tier is a must-read for anyone looking for tips to help them avoid unnecessary costs (and that’s everyone).

Example of a three-tier architecture on AWS

Figure 5. Example of a three-tier architecture on AWS

#5 Announcing updates to the AWS Well-Architected Framework guidance

As usual, Haleh & team are pros at making sure the Well-Architected Framework is current and relevant. Take a look at the enhanced and expanded guidance in all six pillars.

Well-Architected logo

Figure 6. Well-Architected logo

#4 Let’s Architect! Serverless developer experience in AWS

One more winning post from Luca, Federica, Vittorio, and Zamira! This collection of developer resources includes new ideas in AWS Lambda, Amazon Q Developer, and Amazon DynamoDB.

Let's Architect

Figure 7. Let’s Architect

#3 London Stock Exchange Group uses chaos engineering on AWS to improve resilience

This post from April 1 was not an April Fool’s joke! See how LSEG designed failure scenarios to test their resilience and observability.

Chaos engineering pattern for hybrid architecture (3-tier application)

Figure 8. Chaos engineering pattern for hybrid architecture (3-tier application)

#2 Achieving Frugal Architecture using the AWS Well-Architected Framework Guidance

Frugality AND Well-Architected? What a winning combo! This post, inspired by the 2023 re:Invent keynote, outlines the seven laws of Frugal Architecture.

Well-Architected logo

Figure 9. Well-Architected logo

#1 How an insurance company implements disaster recovery of 3-tier applications

And finally, our number one post of the year! Amit and Luiz showcase a customer solution with real-world applications that builds on the guidelines of other posts in this list! Well done!

The Pilot Light scenario for a 3-tier application that has application servers and a database deployed in two Regions

Figure 10. The Pilot Light scenario for a 3-tier application that has application servers and a database deployed in two Regions

Thank you!

As always, thanks to our contributors for their dedication and desire to share, and to you, our readers! We would be nothing with you. Literally.

For other top post lists, see our Top 10 and Top 5 posts from previous years.