Tag Archives: devops

Supercharge your cloud operations with the Kiro power for AWS DevOps Agent

Post Syndicated from Shashiraj Jeripotula original https://aws.amazon.com/blogs/devops/supercharge-your-cloud-operations-with-the-kiro-power-for-aws-devops-agent/

When an alarm fires at 2 AM, the first thing most engineers do is grep logs, check recent deployments, and trace code paths. However, the context they need — metrics, traces, topology, configurations — lives in a separate browser tabs and applications. What if your IDE could bring that cloud intelligence directly to your code, understand the full picture, and help you fix the issue end-to-end? Introducing, The Kiro power for AWS DevOps Agent removes that context switching by connecting your IDE directly to the AWS DevOps Agent, so you can investigate incidents, identify root causes, and generate fixes, all from the same place you write code.

This post is for developers and operators who develop applications using Kiro and want to troubleshoot production issues faster without leaving their editor. We’ll walk through how the power works, what it can do, and a step-by-step example of resolving a real incident.

The Kiro power for AWS DevOps Agent connects Kiro, the AI-powered IDE from Amazon, to the AWS DevOps Agent. It brings the production intelligence and release management in AWS DevOps Agent directly into your development environment — where you already plan, architect, debug, and ship code.

With this power installed, you can review your changes for production risks, investigate production incidents, optimize costs, review architecture, map service topology, and generate remediation code — all through natural language conversation, enhanced with the local context of your workspace.

Challenges in cloud operations today

Operating modern cloud applications means navigating a maze of interconnected services. A single user-facing error might require tracing through Amazon Elastic Container Service (Amazon ECS) tasks, Application Load Balancers, AWS Lambda functions, Amazon DynamoDB tables, and dozens of Amazon CloudWatch metric dimensions. Operators face persistent challenges:

  • Context switching — Investigating an incident requires jumping between the IDE, the AWS Management Console, log viewers, trace explorers, and documentation. Each switch costs time and breaks concentration during high-pressure incidents.
  • Siloed knowledge — Understanding which metrics matter, which services depend on each other, and what “normal” looks like for a given application often lives in runbooks that are outdated or in the heads of senior engineers. New team members face a steep learning curve.
  • Remediation gap — Even after identifying a root cause, translating findings into a working fix — an AWS CloudFormation parameter change, a scaling policy update, or an AWS Identity and Access Management (IAM) policy correction — requires switching contexts again and manually applying changes.
    These challenges compound when teams operate across multiple AWS accounts and environments. Kiro powers address these challenges by bringing operational intelligence directly into the IDE where developers already work.

Challenges in modern software delivery

AI coding agents have changed how fast code gets written, but the code review, testing, and pipeline processes that move code to production were designed for human pace and haven’t kept up. Teams face two persistent challenges:

  • Review capacity — AI-assisted development produces changes faster than human reviewers can evaluate them. Changes that don’t adhere to internal standards, dependency breaks, and access-control gaps that would have been caught by human reviews can slip through at machine pace.
  • Invisible dependencies — Applications span multiple repositories, shared infrastructure, and cross-team API contracts. A parameter rename in one repository silently breaks downstream consumers, and no single reviewer holds the full dependency graph in their head.

Faster code generation without corresponding delivery automation simply moves the bottleneck downstream. The Kiro power for AWS DevOps Agent addresses this by bringing release management intelligence into the IDE so you can review changes for production risks and run exploratory release testing of your web and API applications. Any issues can be immediately mitigated before you even push your code changes.

What are Kiro powers?

A Kiro power is a curated package that gives Kiro specialized capabilities in a specific domain, in this case, AWS operations. When installed, the power provides Kiro with tool connections to your AWS environment, domain-specific knowledge (best practices, error recovery patterns), and instructions for routing your requests to the right workflow. Critically, the power combines your local workspace context (code, git history, configuration files) with cloud-side intelligence (metrics, topology, deployment history) — so Kiro understands both what your code does and how your infrastructure behaves. For a deeper look at the powers framework, see Getting started with Kiro powers

Each power typically includes:

  • MCP server configuration — Connects Kiro to external tools and data through the Model Context Protocol, providing read and write access to cloud resources
  • Steering files — Domain-specific instructions that teach Kiro how to route intents, choose the right workflow, and handle edge cases
  • Contextual knowledge — Domain-specific guidance captured in markdown spec files and lifecycle hooks that encode best practices, common patterns, and error recovery strategies (as described in the blog, Introducing powers).

The Kiro power for AWS DevOps Agent

The Kiro power for AWS DevOps Agent packages the full capabilities of AWS DevOps Agent into a single install for Kiro. Once enabled, Kiro gains the ability to converse with a specialized AI agent that has deep knowledge of your AWS infrastructure, your operational history, and AWS best practices.

You can do the following with this power:

  • Investigate incidents — Describe the symptoms in natural language (“ECS tasks are failing with OOM errors on my-service”) and Kiro orchestrates a deep investigation across CloudWatch metrics, AWS X-Ray traces, Amazon ECS task events, and recent deployments to identify the root cause.
  • Optimize costs — Ask “What cost savings are available for my ECS services?” and receive specific, data-backed recommendations with estimated monthly savings based on actual utilization metrics from your account.
  • Review architecture — Request a topology map or security audit of your services. The agent queries your infrastructure and returns findings with actionable improvement suggestions.
  • Chat across agent spaces — Operate across multiple AWS DevOps Agent agent spaces from a single Kiro session using AWS SigV4. Each agent space can represent a different team, application, or AWS account — and you can switch between them naturally.
  • Generate remediation code — After identifying a root cause, Kiro can generate the fix directly in your workspace. Because it has access to both the investigation findings and your local code, the remediation is specific to your application, not generic boilerplate.
  • Run a release readiness review — After finishing a batch of code changes, have the DevOps Agent review the changes for dependency risks, deviations from your standards and best practices, and expansion of access controls in CloudFormation that go beyond best practices. It also builds and runs your code in an AWS-managed sandbox to better assess any production risks.
  • Perform exploratory release testing for deployed applications — If you deploy your web or API application to a production-like environment, Kiro can have the DevOps Agent run an exploratory tests on it. Any bugs or regressions found can be fixed without leaving the IDE.

How it works

The power provides two complementary workflows that Kiro selects automatically based on your request:

  • Chat (updates in seconds) — For instant answers about cost, architecture, topology, and knowledge discovery. Kiro creates a conversation with the DevOps Agent and streams responses in real time. Follow-up questions retain full context within the same session.
  • Investigation (completes in minutes) — For complex incidents requiring deep analysis. The DevOps Agent examines CloudWatch metrics, X-Ray traces, deployment history, and service topology, then delivers a root cause analysis with prioritized recommendations.

The following diagram shows how Kiro combines local workspace context with the DevOps Agent’s cloud intelligence:
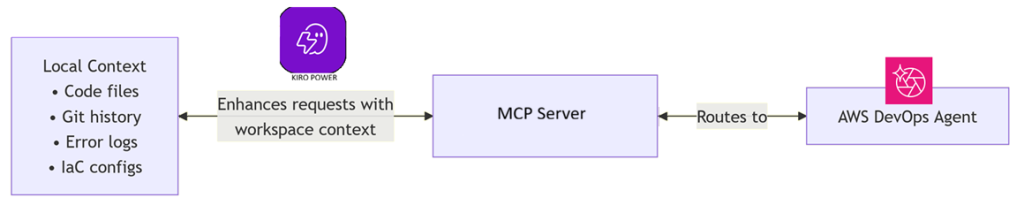
Kiro combines local workspace context with the DevOps Agent's cloud intelligence through the AWS DevOps Agent MCP Server.

Figure 1: Kiro combines local workspace context with the DevOps Agent’s cloud intelligence through the AWS DevOps Agent MCP Server.

Prerequisites

Before using the power, ensure you have:

  1. AWS credentials configured (AWS IAM Identity Center recommended) if using AWS SigV4.
  2. Kiro installed and a workspace set up
  3. An AWS DevOps Agent agent space configured with data sources (CloudWatch, X-Ray, or other integrations)
  4. Create an access token or have AWS SigV4 configured. The access tokens feature must be enabled on your Agent Space for access tokens to work.
  5. For access tokens, you must have IAM permissions to manage access tokens (aidevops:CreateAccessToken, aidevops:RevokeAccessToken, aidevops:RotateAccessToken).
    • Enable access tokens
      • Review the security best practices detailed in the connect to DevOps Agent Remote Server documentation.
      • Sign in to the AWS Management Console and open the AWS DevOps Agent console.
      • Choose your Agent Space.
      • Choose the Configuration tab.
      • In the Access tokens section, choose Enable.
      • Confirm the action.
    • Create a token
      • Open the DevOps Agent web app for your Agent Space, then from the navigation menu, choose Settings, then choose Access Tokens.
      • Choose Create access token.
      • Enter a name for the token.
      • Choose a scope:
      • read – View investigations, recommendations, chats, and Agent Space resources.
      • operate – Full access. Includes everything in read, plus send messages, create chats, and manage backlog tasks and recommendations.
      • Set an expiration (1 to 60 days).
      • Copy the token value and store it in a safe, secure location. You cannot retrieve it again.
      • After creating a token, the web app displays a configuration example that you can copy directly into your client.

The power works with any agent space that has active data sources. The more data sources connected, the richer the investigations and recommendations.

Getting started with the Kiro power for AWS DevOps Agent

Setting up the power takes only a few steps. You can install it directly or follow these steps:

  1. Open Kiro and choose the Powers icon in the sidebar.
  2. In the AVAILABLE panel, find AWS DevOps Agent.
  3. Choose Install.
  4. The power appears in the INSTALLED panel, and choose Try power.
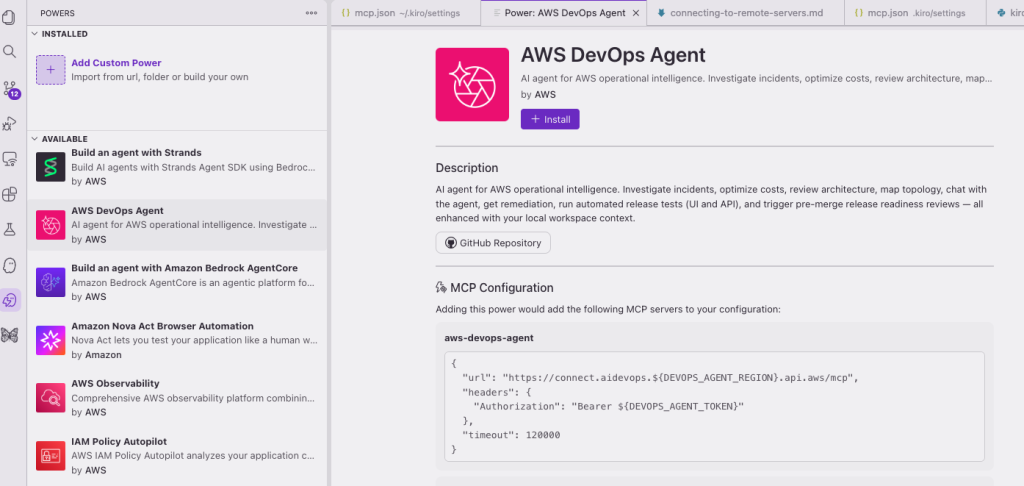
Kiro powers panel showing the Kiro power for AWS DevOps Agent

Figure 2: Kiro powers panel showing the Kiro power for AWS DevOps Agent

Verify Installation

After installation, you should see the Kiro power for AWS DevOps Agent listed in the powers section of the Kiro panel. Navigate to mcp.json file and change these values accordingly, and save the config file.

  • DEVOPS_AGENT_TOKEN=<your-token>
  • DEVOPS_AGENT_REGION=<your-agent-space-region>

In the MCP Servers panel, you will see DevOps Agent MCP connected and also displays list of tools. The power activates automatically when you mention relevant keywords like incident, cost optimization, architecture review, or topology in your conversation.
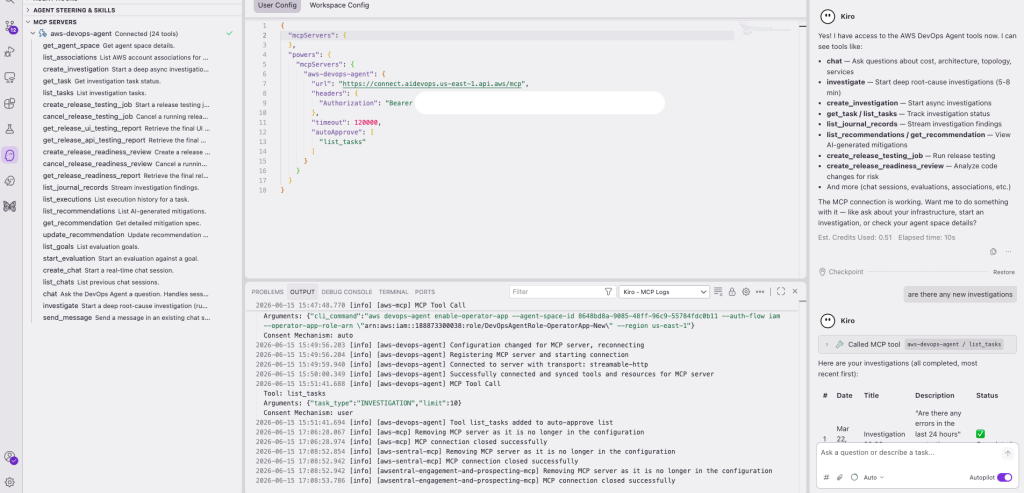
Figure 3: MCP Servers panel showing the AWS DevOps Agent MCP and connected tools

Figure 3: MCP Servers panel showing the AWS DevOps Agent MCP and connected tools

Walkthrough: Investigating a production incident

Let’s walk through a realistic scenario. Your team receives a CloudWatch alarm: an Amazon ECS service is returning HTTP 503 errors and task restarts have spiked.

Step 1: Describe the problem

In Kiro, you type:

“My ECS service checkout-api is throwing 503 errors. The alarm fired 10 minutes ago. Here’s the error from my logs: Connection pool exhausted, max connections 50 reached.”

Because Kiro has access to your workspace, it automatically includes relevant context — your task definition, your connection pool configuration from application.yml, and your recent git commits.

Step 2: Kiro starts the investigation

Kiro routes this to the investigation workflow. You see real-time progress as findings stream in:

  • Planning investigation approach…
  • Querying CloudWatch metrics, ECS task events, X-Ray traces…
  • Analyzing connection pool metrics against task count…
  • Root cause identified: Connection pool sized for single task, but service scaled to 5 tasks sharing a database connection limit

Step 3: Review findings and recommendations

The DevOps Agent returns a detailed analysis:

Root cause: The database connection limit (50) is shared across all ECS tasks. When the auto-scaling policy added tasks at 08:47 UTC, each task attempted to open 50 connections, exceeding the Amazon RDS max_connections parameter (100).

Recommendation and Mitigation: Reduce the per-task connection pool to max_connections / max_tasks (100 / 5 = 20 per task), or increase the RDS instance class to support more connections.

Step 4: Generate and apply the fix

You ask Kiro to implement the recommendation. Because it has access to your application.yml and your AWS CloudFormation template, it generates a targeted fix:

  • Updates spring.datasource.service.maximum-pool-size from 50 to 20 in your application configuration
  • Adds a comment explaining the calculation
  • Suggests an RDS parameter group change if you want to increase capacity instead

The fix is applied directly in your workspace, ready for review and commit.

Operating across multiple agent spaces

If your team manages multiple applications, each with its own DevOps Agent agent space, you can switch between them naturally. Kiro lists available agent spaces and routes your question to the right one.

Conclusion

The Kiro power for AWS DevOps Agent brings the full operational intelligence of AWS DevOps Agent into the IDE where you already work. By combining your local workspace context with cloud-side analysis, it closes the loop from detection to remediation without context switching.

Whether you are triaging a production incident, optimizing costs across services, or onboarding a new team member who needs to understand your infrastructure, the power provides contextual answers grounded in your actual AWS environment.

Install the Kiro power for AWS DevOps Agent today and experience AI-powered cloud operations in your IDE. To learn more, visit the Interfacing with AWS DevOps Agent and the Kiro powers documentation.
Tipu Qureshi Tipu Qureshi
Tipu Qureshi is a Senior Principal Technologist in AWS Agentic AI, focusing on operational excellence and incident response automation. He works with AWS customers to design resilient, observable cloud applications and autonomous operational systems.
Shashiraj Jeripotula (Raj) Shashiraj Jeripotula (Raj)
Shashiraj Jeripotula (Raj) is a San Francisco-based Principal Partner Solutions Architect at AWS. He works with ISV and AWS partners to build deep integrations across observability, AI, and agentic development tooling — helping developers leverage AI agents, Model Context Protocol (MCP), and shift-left observability to build responsible, production-ready AI systems on AWS.


AWS DevOps Agent adds release management capabilities to assess code changes before production (preview)

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/aws-devops-agent-adds-release-management-capabilities-to-assess-code-changes-before-production-preview/

Today, we’re announcing a new release management capability in AWS DevOps Agent that is now available in preview. AWS DevOps Agent is your always-available teammate that spans software changes and operations across AWS, multicloud, and on-premises environments. The practice of DevOps aims to make software change and operations smooth and increasingly autonomous, and AWS DevOps Agent delivers on both by leveraging its deep understanding of your environment, your services, their dependencies, and how they behave in production. Already generally available for post-deployment operations, it autonomously investigates incidents, provides root cause analysis and mitigation steps, and delivers targeted recommendations to prevent recurring issues. With today’s preview, AWS DevOps Agent adds release readiness review of code changes and autonomous release testing. These new features verify every change against the natural language standards you give to the DevOps Agent and run change-specific tests in production-like environments. AWS DevOps Agent now supports teams from code creation to production, helping reviewers and testers keep pace with the volume of AI-generated code.

As development teams adopt AI coding tools, the volume of pull requests moving through delivery pipelines has increased faster than review and testing processes can handle. When teams are under pressure to keep up, reviews are approved without thorough examination, and test environments drift from production. The value that coding agents generate sits waiting in review queues instead of reaching end users. At the same time, AI models are increasingly capable of catching functional and security issues that human reviewers might miss under time pressure, making speedy and safe delivery a requirement rather than a tradeoff.

The release readiness review feature evaluates every code change against production requirements, dependency safety, and the standards and best practices you provide to the DevOps Agent. The agent checks cross-repository dependency risks that could affect other services, access control changes against AWS Well-Architected Framework best practices, and compliance with any standards you have defined. When no standards are provided, the agent applies general best practices. As part of the review, the agent also runs your software in an AWS-managed isolated environment, executing lightweight user journey tests to verify the software builds, runs, and passes basic functional checks before the change enters the pipeline. Findings appear in the AWS DevOps Agent console and as comments on pull requests in GitHub or GitLab. You can also invoke reviews directly from your IDE through the Kiro power or Claude Code plugin, so developers can identify and fix dependency risks, standards violations, and access control issues before the change is committed to version control.

The autonomous release testing feature goes further, generating and running change-specific test plans for web and API-based applications in customer-provisioned, production-like environments before the change merges. Rather than running a static test suite, the agent reasons about what the change does and constructs tests tailored to it, covering functional correctness, behavioral regressions, and integration scenarios that a manually maintained test plan might not anticipate. Every test run produces structured artifacts including metrics, logs, traces, and an execution summary, giving reviewers a consistent record of what was tested and what the results were.

Getting started with AWS DevOps Agent release management
This walkthrough shows how to run an on-demand release readiness review using the AWS DevOps Agent web app. Before you begin, confirm that you have at least one GitHub or GitLab repository connected to your Agent Space. Once your repositories are connected, AWS DevOps Agent will index your code and build a knowledge graph of cross-repository and cloud dependencies.

To open the web app, navigate to the AWS DevOps Agent console, select your Agent Space, and choose the Web app tab. Choose Operator access to open the web app.

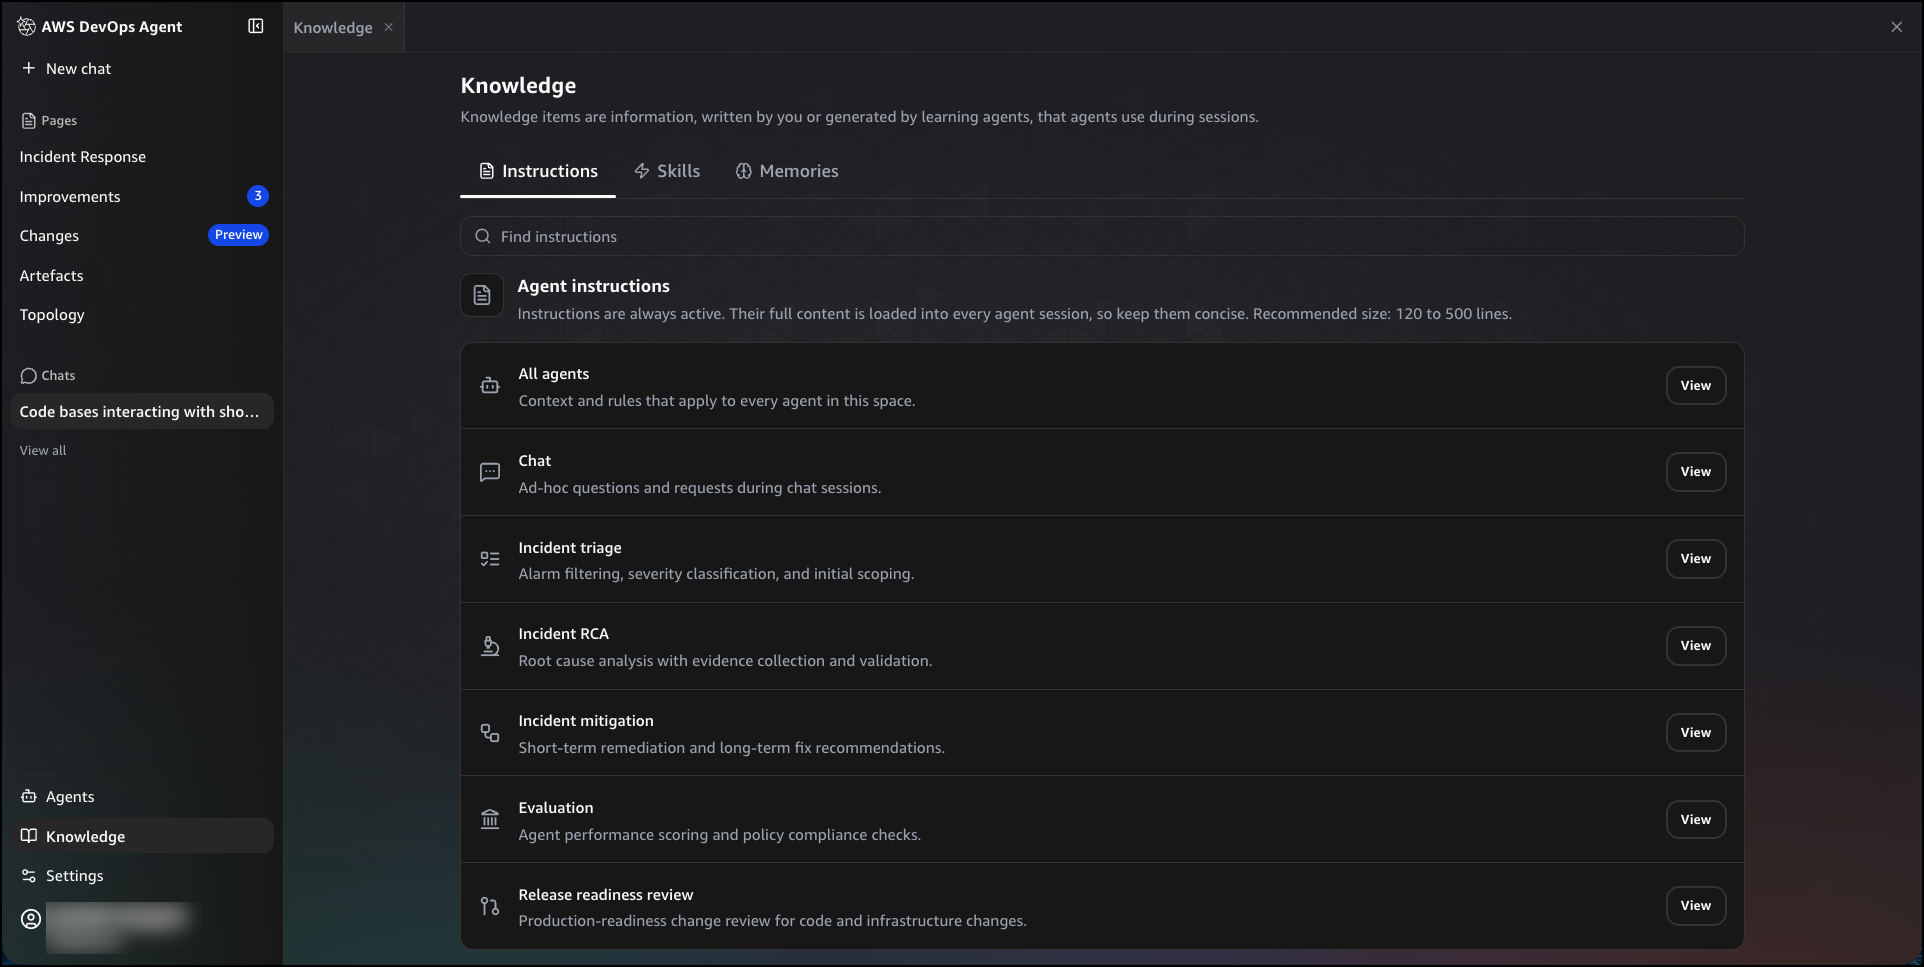
Without standards configured, the agent applies general best practices. To tailor reviews to your internal standards, navigate to Knowledge, then choose the Instructions tab. You will see a list of instruction sets, each scoped to a specific agent or task. Choose View next to Release readiness review to edit the instructions for production-readiness change review. Write your internal standards in plain English. For example, you can define infrastructure and data standards on encryption or network access rules, best practices that warn without blocking such as logging and observability requirements, and sensitive data classification best practices that identify applications or resources requiring higher security measures. To apply instructions across all agents in your space, choose View next to All agents.

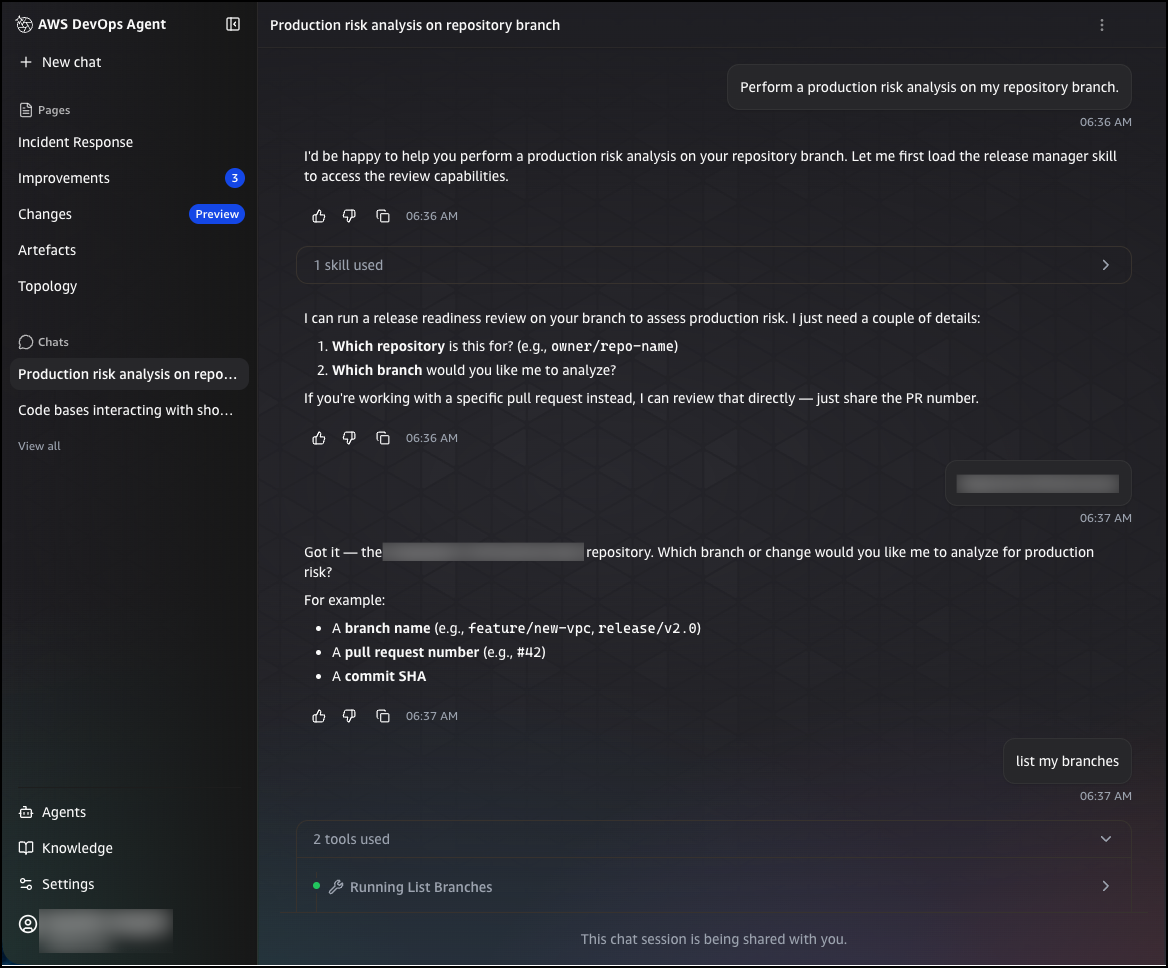
You can trigger a release readiness review in two ways: by submitting a pull request to a connected repository, or by entering an on-demand query in the chat interface. To run an on-demand review from chat, choose New chat and enter a request such as:

Perform a production risk analysis on my repository branch

The agent will ask for the repository and branch you want to analyze. You can provide a branch name, a pull request number, or a commit SHA. Once you confirm your selection, the agent queues the review and analyzes the change for production risks, including infrastructure impacts, configuration changes, and potential issues.

After the review completes, you can ask follow-up questions directly in the chat to explore the findings in more detail. For example, you can ask which downstream consumers a change affects, and the agent will return a structured breakdown of in-repository and cross-repository consumers that will break, the specific files and line numbers affected, and the recommended steps to resolve the issue before deployment.

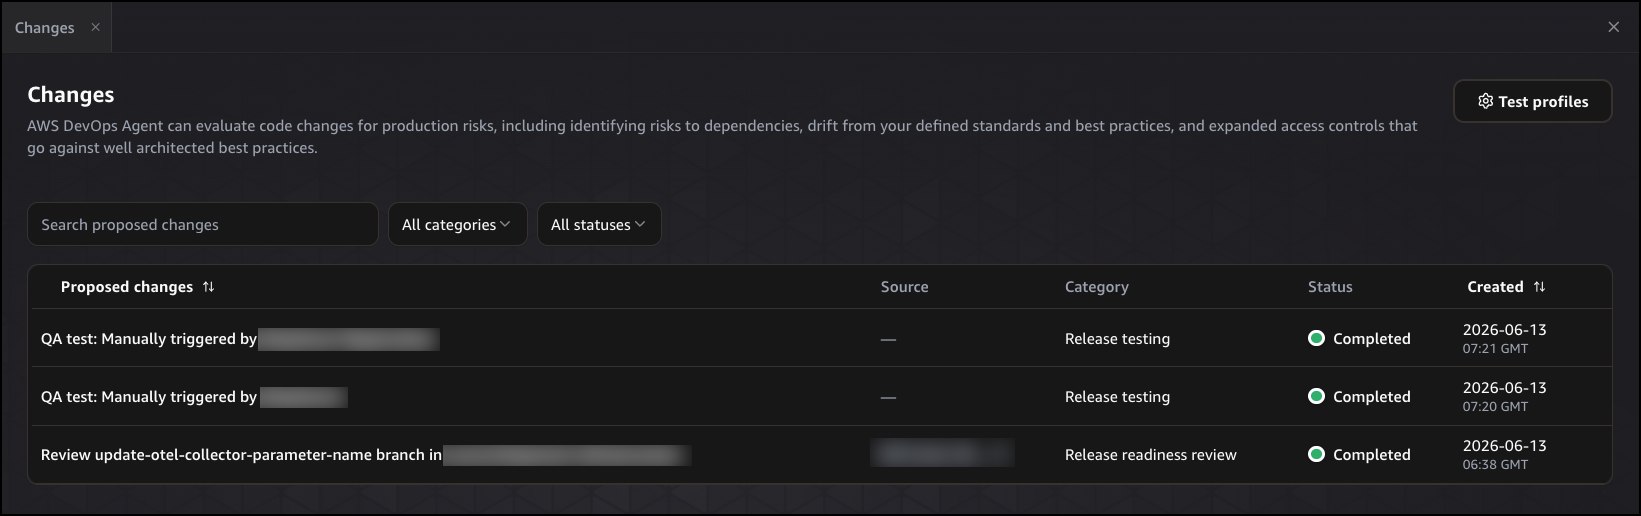
After submitting a review request, navigate to Changes in the left navigation pane. The Proposed changes table shows each review that has run, including the proposed change description, its source, category, status, and when it was created. You can filter by category or status to find specific reviews, or search by name using the search bar. Choose any entry to open the full execution detail.

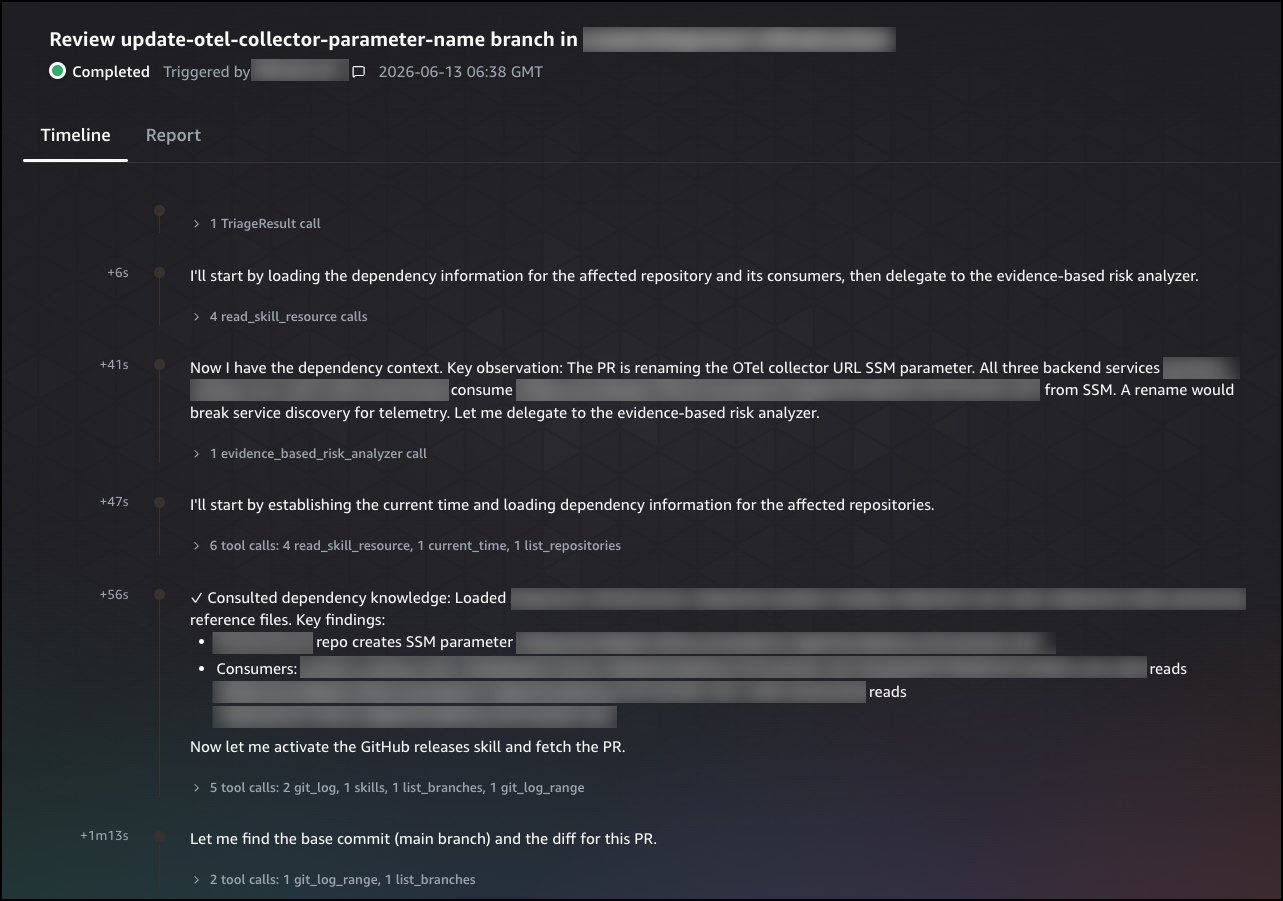
The Timeline tab shows the agent’s step-by-step reasoning process, including the tools it called, the dependencies it consulted, and the observations it made at each step. Each entry is timestamped, giving you a complete record of how the agent built its understanding of the change and reached its conclusion.

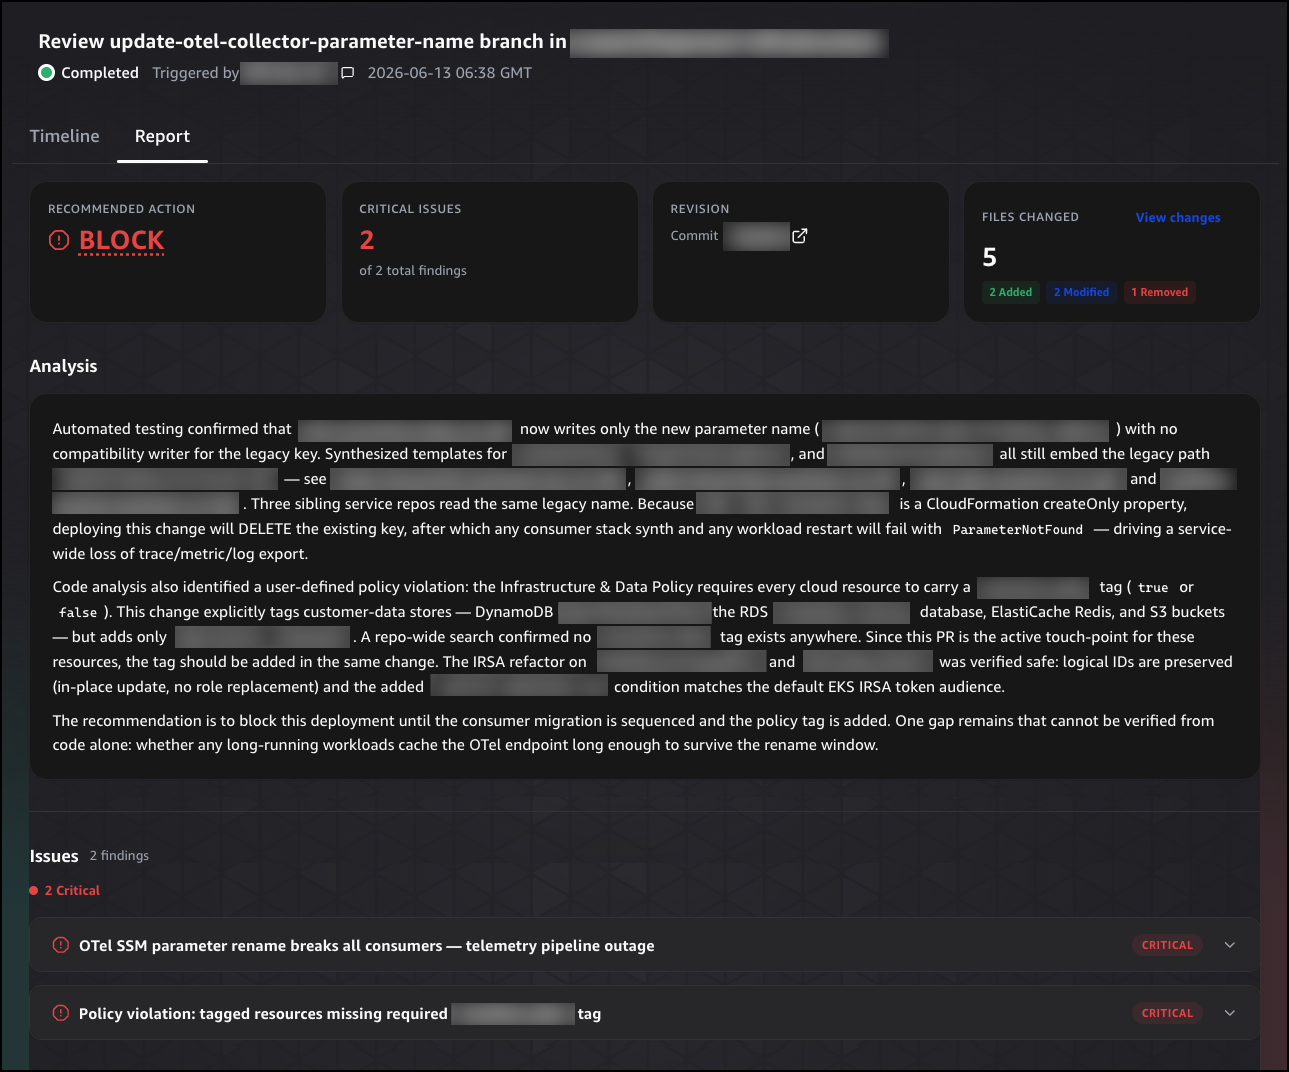
Choose the Report tab to see the final recommendation. The report opens with a summary header showing the recommended action, the number of critical issues found, the commit revision, and the number of files changed. The recommended action is either BLOCK, Proceed with Caution, or Safe to Release.

Below the summary header, the Analysis section explains why the recommendation was made, citing specific risks and the evidence the agent found to support its conclusion. The Issues section lists each finding by severity, giving you a prioritized view of what needs to be addressed before the change can proceed. The Recommendations section provides specific, actionable steps the developer can take to resolve each issue. Finally, the Changes section lists each file that was modified, with the type of change, the category it falls under, and a description of what was changed, so reviewers have a complete picture of what the change does before it merges.

You can also invoke the autonomous release testing feature directly from the chat interface. To run an autonomous release test on a web or API-based application, choose New chat and enter a query such as:

Run a release test on my application deployed at [application URL]

The agent generates a change-specific test plan and executes it in your provisioned environment. Results appear in Changes, where you can review the execution steps and a structured summary of what was tested.

Get started today
The release readiness review and autonomous release testing features for AWS DevOps Agent are available in preview. These features are available at no additional cost during preview in the US East (N. Virginia) Region. For pricing information on other AWS DevOps Agent features, visit the AWS DevOps Agent pricing page.

For configuration details, visit the AWS DevOps Agent user guide.

— Esra

Accelerate Incident Resolution with PagerDuty and AWS DevOps Agent

Post Syndicated from Shan Kandaswamy original https://aws.amazon.com/blogs/devops/accelerate-incident-resolution-with-pagerduty-and-aws-devops-agent/

When something breaks in production, you find out fast. Understanding why it broke, before the damage spreads, is the hard part. That is where Site Reliability Engineering (SRE) teams lose the most time.

Think about the last time you got paged at 2 a.m. The alert said something broke, not why. You open four or five dashboards, cross-reference deployment logs with AWS CloudTrail events, and scroll through metrics. Twenty or thirty minutes burn before the picture comes together. That manual correlation is where resolution time balloons.

What if the investigation started before you opened your first dashboard?

That’s the idea behind connecting the new native PagerDuty Capability Provider in AWS DevOps Agent. The two systems now talk directly over a built-in OAuth 2.0 connection. When a PagerDuty incident triggers, the DevOps Agent starts investigating while responders are still getting oriented. Connecting them takes a few fields in a console.

What AWS DevOps Agent does

AWS DevOps Agent is a frontier agent built to help engineering teams investigate and resolve production incidents faster. The DevOps Agent works as a first responder, conducting federated investigations across your observability stack, tracing incidents from code changes all the way through to cloud infrastructure impact, and producing detailed mitigation plans. Beyond reactive investigations, it also proactively recommends improvements to your observability, infrastructure, and deployment pipelines to help prevent recurring issues. Through the AWS DevOps Agent web app, you can observe investigations as they unfold, access findings, and steer the analysis in real time.

The central concept is the Agent Space. Think of it as the boundary that defines what your agent can access. Your AWS account serves as the primary source, and from there you layer on secondary capabilities from telemetry providers like Datadog, Dynatrace, New Relic, or Splunk; pipeline tools like GitHub and GitLab; communications from PagerDuty and Slack; and custom Model Context Protocol (MCP) servers for anything else. Every investigation the agent runs, it learns. It maps relationships between your resources such as load balancers to services, services to databases, and deployments to config changes. One team we’ve worked with had the agent map hundreds of infrastructure relationships, and that number keeps growing with each investigation it completes.

PagerDuty, of course, needs no introduction to anyone who’s been responsible for resolving critical, customer-impacting incidents. Engineering teams rely on it to detect, triage, resolve, and learn from incidents. The native PagerDuty Capability Provider in AWS DevOps Agent connects the two directly. PagerDuty incident events drive AWS DevOps Agent investigations automatically. Findings flow back to the originating PagerDuty incident record, including root cause analysis and recommended mitigation steps. They are also available in the AWS DevOps Agent console and web app, giving your whole team visibility into what the agent discovered.

There’s a second piece to this integration worth understanding. By adding the PagerDuty MCP Server as a capability and configuring an AWS DevOps Agent skill for working with PagerDuty, you enable AWS DevOps Agent to query PagerDuty’s institutional memory during investigations. This includes past incidents, diagnostics, resolution patterns, and operational context across both AWS and non-AWS environments. This PagerDuty MCP Server-based connection is separate from the Capability Provider event flow and requires its own setup (covered in Step 6 below). The result is investigations informed by both current signals and prior incident history.

Why this matters

These are practical, tangible changes for your team:

Faster time to root cause. When a PagerDuty incident triggers, AWS DevOps Agent kicks off an investigation automatically. No one has to sign in to another tool, step through a wizard, or remember to initiate anything. The investigation is already running by the time you acknowledge your alert.

Real contextual analysis. The agent correlates PagerDuty incident data with Amazon CloudWatch metrics, AWS CloudTrail logs, application topology, and deployment history, plus telemetry from whichever third-party observability providers you’ve connected, like Datadog, Splunk, New Relic, or Dynatrace. It connects dots that would otherwise take humans significant time to even start connecting.

Investigations start when an incident triggers. AWS DevOps Agent automatically conducts the deep-dive investigation behind the scenes. It reports back its root cause analysis and proposed mitigation steps into the originating PagerDuty incident, with a link to the AWS DevOps Agent web app for more details.

Less time playing detective, more time fixing things. That manual data correlation across four or five tools? The agent handles it. Your people can focus on actually resolving the issue instead of building the investigation timeline by hand.

Nothing extra to host. The native PagerDuty Capability Provider means you’re not standing up additional infrastructure. No servers to manage, no endpoints to maintain on your side.

How the integration works

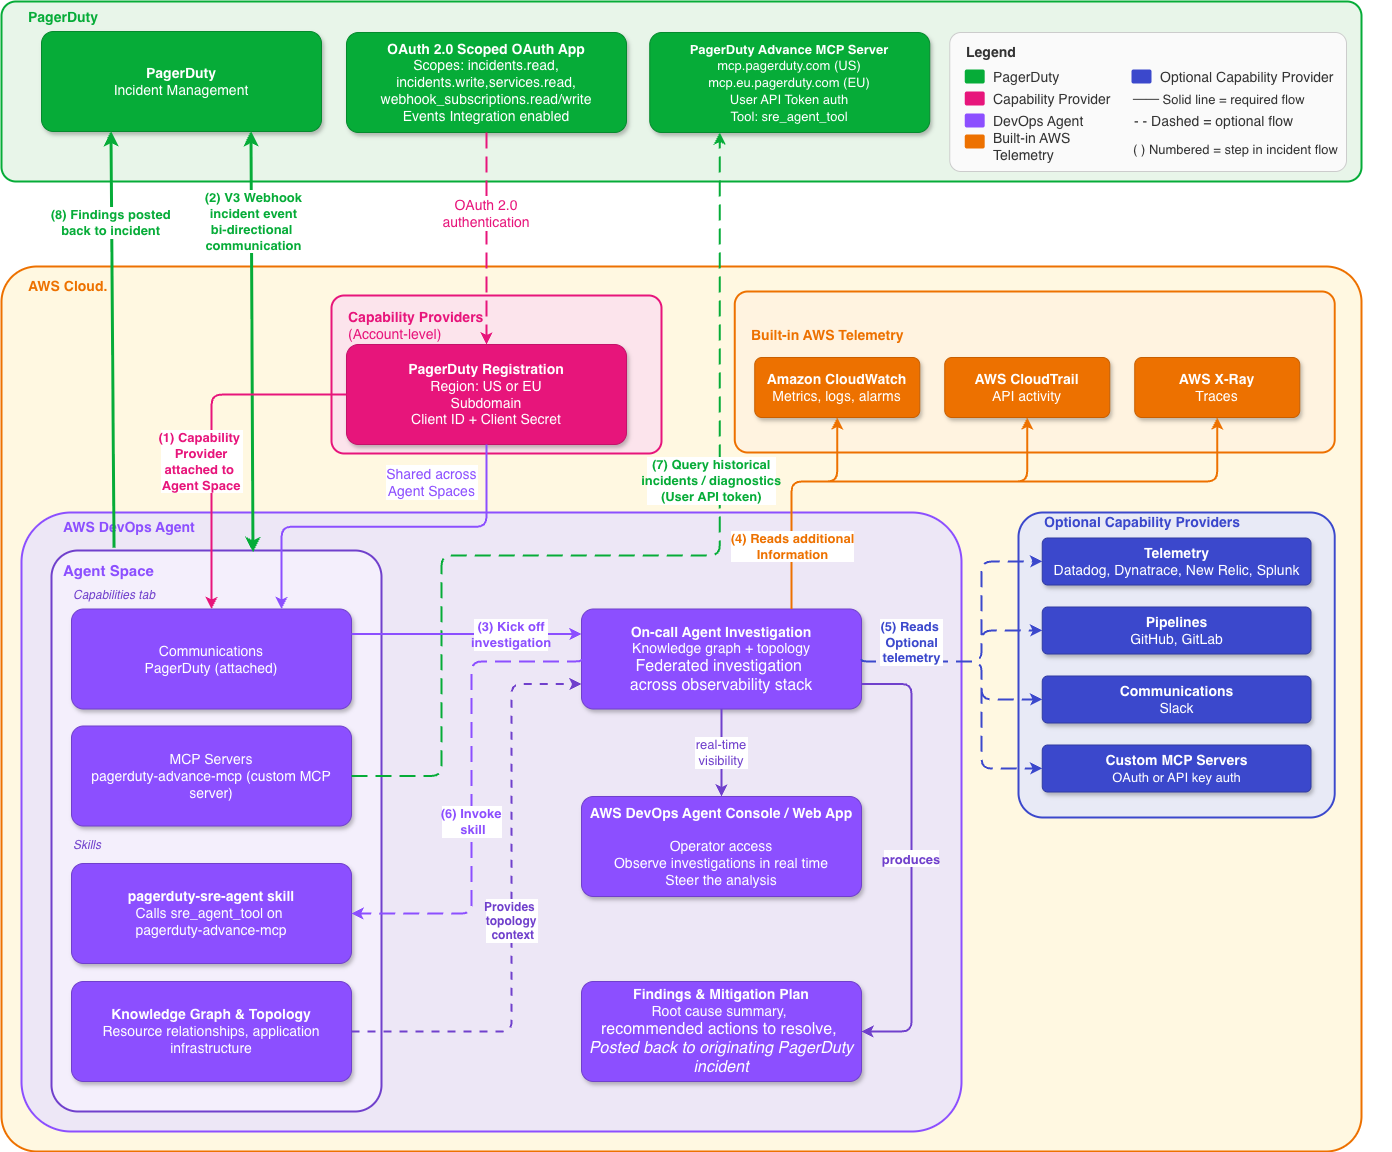
The architecture is straightforward. Here’s the flow:

High-level architecture diagram showing PagerDuty connected to AWS DevOps Agent through a native OAuth 2.0 Capability Provider, with the agent investigating across AWS CloudWatch, AWS CloudTrail, and connected telemetry and pipeline tools

Figure 1: High-level architecture, native PagerDuty Capability Provider in AWS DevOps Agent.

AWS DevOps Agent and PagerDuty authenticate to each other using OAuth 2.0 Scoped OAuth. You register PagerDuty once at the AWS account level as a Capability Provider, and then add it to whichever Agent Spaces need it. Registration is shared across Agent Spaces in the account, so you don’t have to repeat the setup per team.

Once a PagerDuty incident triggers, AWS DevOps Agent picks up the event over the native connection and begins investigating:

  1. Receives the PagerDuty incident event (service, severity, and initial context) via the native Capability Provider connection
  2. If the PagerDuty MCP capability and AWS DevOps Agent skill are configured, queries PagerDuty for related historical incidents, past diagnostics, and resolution patterns to enrich the investigation
  3. Examines AWS resource topology and the relationships between your infrastructure components through its knowledge graph
  4. Reviews AWS CloudTrail logs for recent changes or anything that looks off
  5. Queries Amazon CloudWatch and connected telemetry providers (Datadog, Dynatrace, New Relic, Splunk) for relevant metrics and traces
  6. Cross-references deployment events from configured pipeline tools (GitHub, GitLab) against the incident timeline
  7. Synthesizes potential root causes from all the evidence it’s gathered

The agent builds up a comprehensive picture by introspecting AWS observability data, pulling from connected capability providers, and leveraging the topology mapping that creates a knowledge graph of your application infrastructure. Every investigation it runs expands its understanding of how your resources connect. It discovers relationships you might not have explicitly documented, building a richer map with each incident it works.

Beyond raw data, the agent produces detailed mitigation plans with specific actions to resolve the issue, validate the fix, and revert if needed. The agent posts its findings, root cause summary, and recommended next steps directly to the originating PagerDuty incident record, giving your on-call team actionable information without them having to go digging.

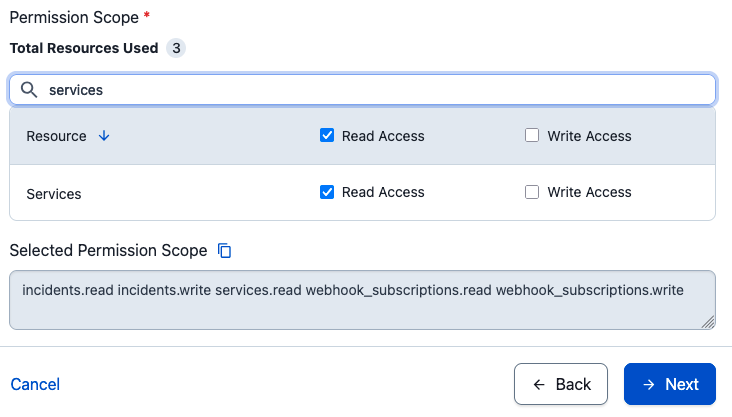
A quick note on security, because it matters. The native connection uses OAuth 2.0 Scoped OAuth with a minimum set of PagerDuty scopes (incidents.read incidents.write services.read webhook_subscriptions.read webhook_subscriptions.write). AWS DevOps Agent only supports the newer scoped OAuth flow; legacy PagerDuty OAuth with a redirect URI is not supported. For inbound events from PagerDuty, only V3 webhooks are supported. Earlier webhook versions won’t work. Traffic flows over HTTPS.

Getting it set up

Setup comes in four phases: register PagerDuty as a Capability Provider at the account level, attach it to your Agent Space, configure the PagerDuty MCP server and AWS DevOps Agent skill for working with PagerDuty to enrich investigations, and verify things work end to end.

What you’ll need

  • An active AWS account with permissions to use AWS DevOps Agent
  • AWS DevOps Agent enabled in a supported AWS Region. You’ll create an Agent Space, which needs two AWS Identity and Access Management (IAM) roles (one for Agent Space operations, one for web app functionality). Both can be auto-created during setup
  • A PagerDuty account with permission to register OAuth apps, plus an Administrator role for Events Integration
  • A PagerDuty Advance license and a PagerDuty User API token (for the MCP integration in Step 6)
  • Your PagerDuty account subdomain (so if your PagerDuty URL is https://your-company.pagerduty.com, the subdomain is your-company)
  • An OAuth client ID and client secret from a PagerDuty app registered with OAuth 2.0 Scoped OAuth

Step 1: Create your Agent Space

Stand up an Agent Space in the AWS DevOps Agent console. This defines the boundary for what the agent can reach into and investigate.

  1. Head to the AWS DevOps Agent console home page.
AWS DevOps Agent console home page with a Begin setup call to action to create your first Agent Space

AWS DevOps Agent console home page.

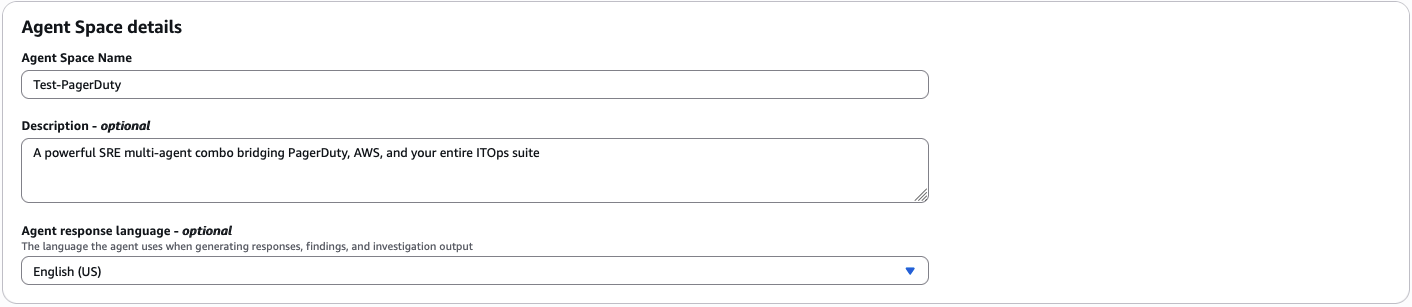
  1. Create a new Agent Space with a name and a short description, usually scoped to a service or application team’s responsibilities
Create Agent Space form with fields for Agent Space name, optional description, and agent response language

Creating a new Agent Space with a name and description.

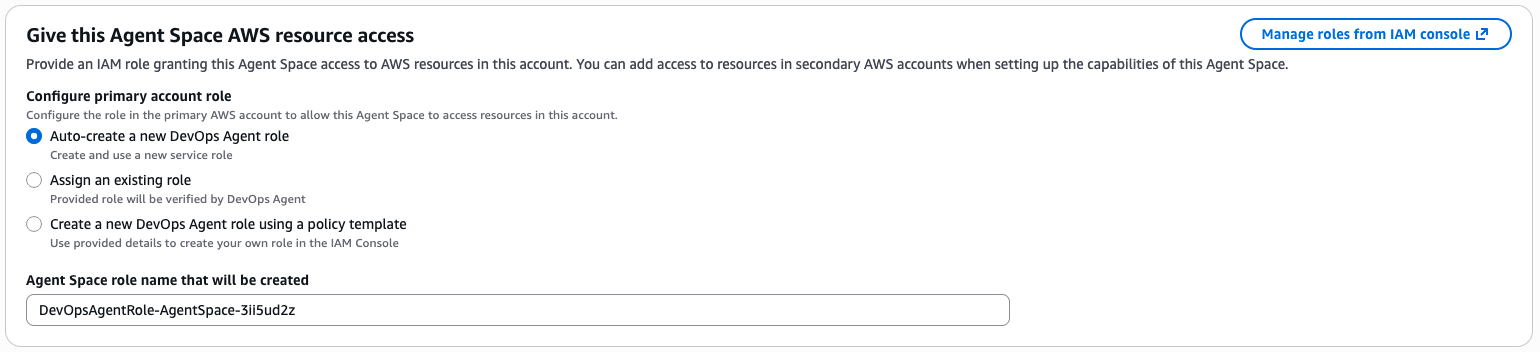
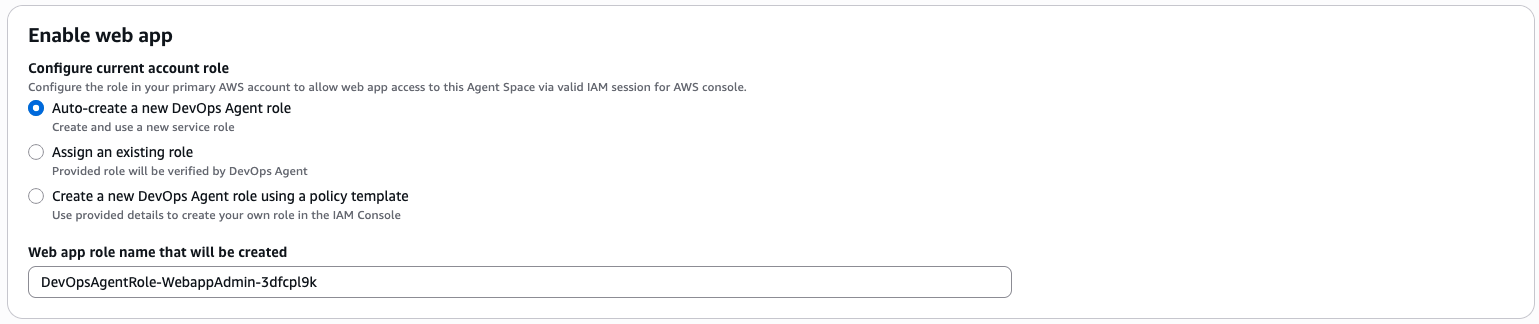
  1. Create the Agent Space IAM roles (AWS DevOps Agent requires two IAM roles: one for Agent Space operations and another for its associated web app functionality). You can auto-create them during setup
Agent Space setup screen showing the two IAM roles required, one for Agent Space operations and one for web app functionality

Configuring the two IAM roles required for the Agent Space.

Detailed view of IAM role auto-creation options during Agent Space setup

IAM roles can be auto-created during setup.

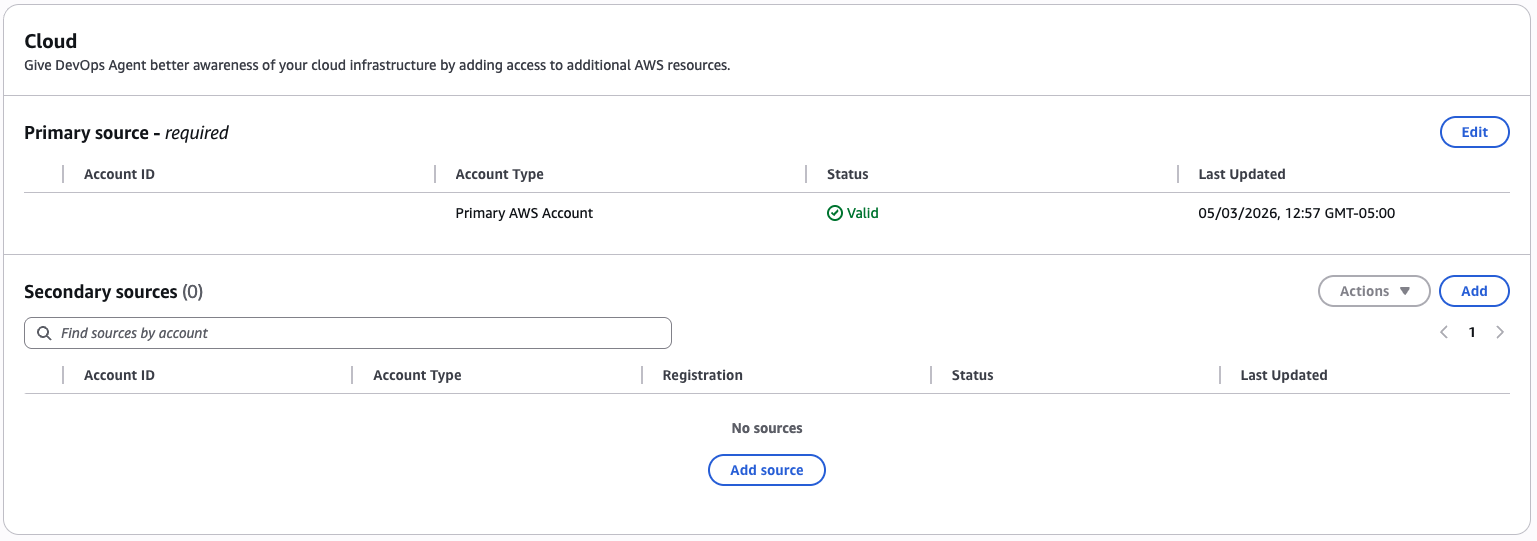
  1. Your primary source (the AWS account you’re creating the Agent Space in) is added automatically. If you need the agent to investigate resources in other accounts, add those as secondary sources
Agent Space sources screen showing the AWS account added automatically as the primary source

The AWS account is added automatically as the primary source.

Step 2: Add supporting capabilities

Out of the box, the agent connects to Amazon CloudWatch for metrics, logs, and alarms, and can investigate AWS CloudTrail API activity and AWS X-Ray traces through its read-only permissions. That said, most teams don’t live entirely inside AWS tooling, and that’s where third-party capability providers pull their weight. You can wire in external tools to give the agent a fuller picture of your world:

  • Telemetry: Datadog, Dynatrace, New Relic, or Splunk, so the agent can pull metrics and traces beyond Amazon CloudWatch during investigations
  • Pipelines: GitHub or GitLab, so it can correlate deployments and code changes with incidents
  • Communications: Slack, for team coordination and investigation updates (PagerDuty is configured separately as a Capability Provider in Step 4)
  • MCP Servers: Custom integrations via OAuth or API keys for anything else in your stack

You don’t need everything connected on day one. Start with what makes sense and add more as you go. Each new capability helps the agent discover more infrastructure relationships and investigate more effectively.

Step 3: Set up application topology

Help the agent understand what your application landscape looks like:

  1. Configure IAM roles to define the AWS topology scope for your Agent Space. The agent uses these permissions to determine which resources it can see and investigate
  2. Give the agent time to discover and map the relationships between your resources (it does this automatically as it runs investigations)
  3. Check the interactive topology visualization in the console and make sure your critical components are showing up correctly
  4. If you want the agent to focus on certain tags or resource subsets, add those instructions to your skills

Step 4: Register PagerDuty as a Capability Provider

You register PagerDuty once at the AWS account level. From there, it’s shared across every Agent Space in the account.

First, create the OAuth app in PagerDuty:

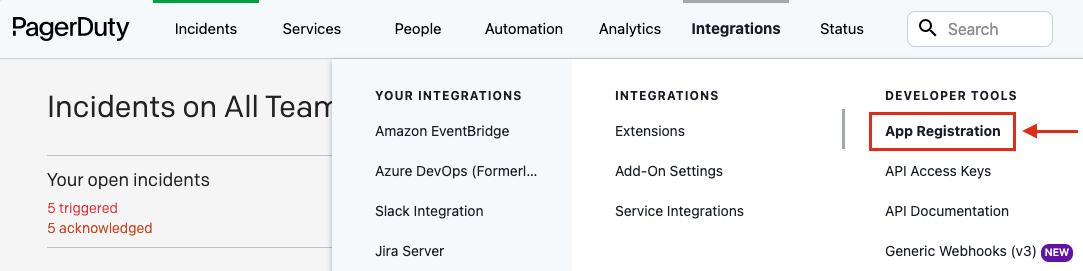
  1. In a separate browser tab, sign in to PagerDuty and go to Integrations > App Registration
PagerDuty Integrations menu showing the App Registration option

In PagerDuty, navigate to Integrations then App Registration.

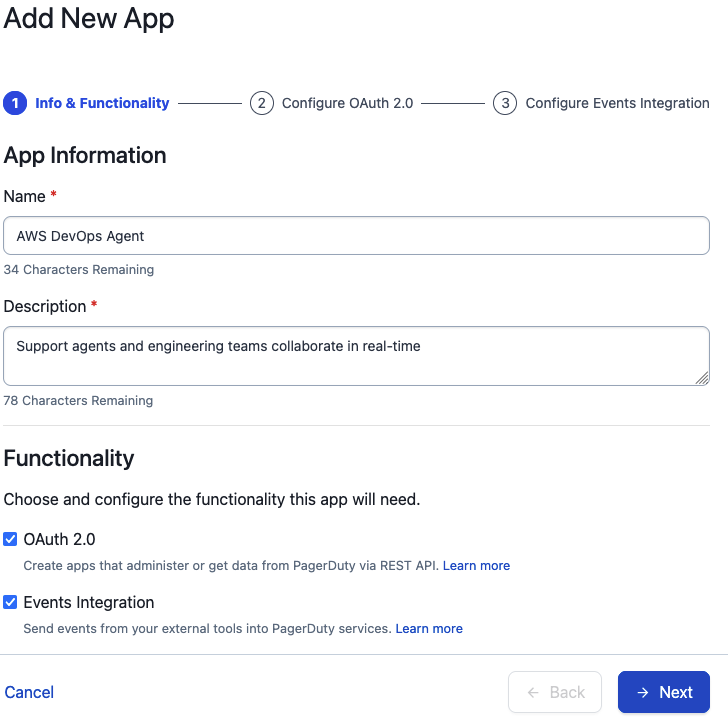
PagerDuty App Registration page for creating a new app

PagerDuty App Registration page.

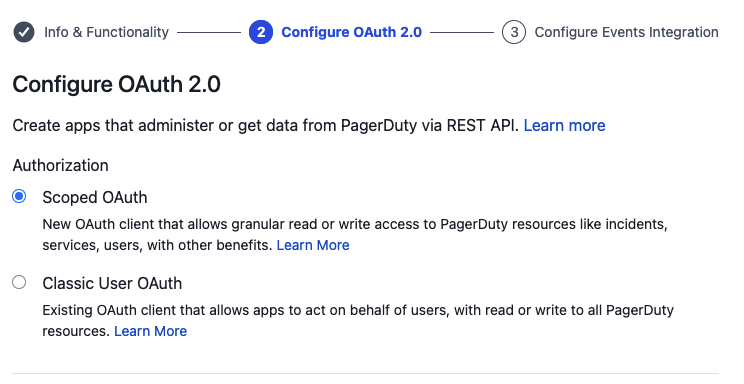
  1. Create a new app using OAuth 2.0 Scoped OAuth. AWS DevOps Agent does not support legacy PagerDuty OAuth with redirect URI
PagerDuty new app form with OAuth 2.0 Scoped OAuth selected as the authentication type

Create the app using OAuth 2.0 Scoped OAuth.

  1. Under Permissions, grant the minimum scopes: incidents.read incidents.write services.read webhook_subscriptions.read webhook_subscriptions.write
PagerDuty OAuth permissions screen showing the minimum required scopes for incidents, services, and webhook subscriptions

Granting the minimum required OAuth scopes.

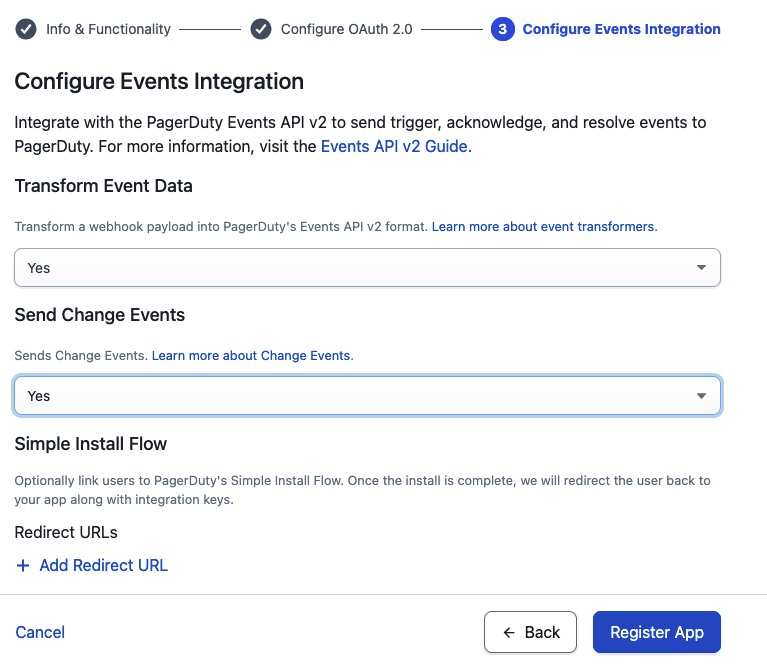
  1. Turn on Events Integration so AWS DevOps Agent and PagerDuty can talk in both directions
PagerDuty app configuration with Events Integration enabled

Turn on Events Integration for two-way communication.

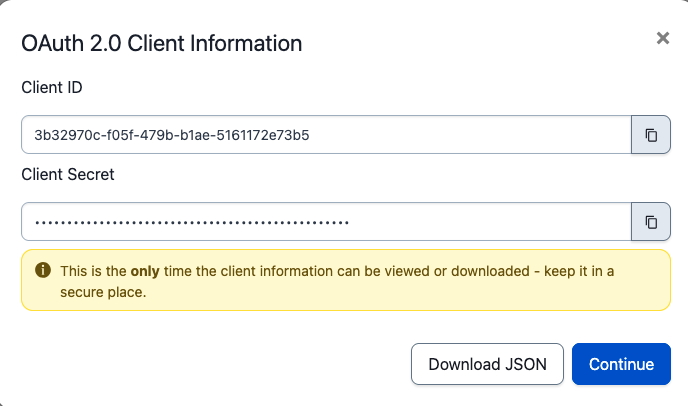
  1. Copy your Client ID and Client Secret. You’ll paste them into the AWS console in a minute
PagerDuty app credentials screen displaying the Client ID and Client Secret

Copy the Client ID and Client Secret from PagerDuty.

Then, register PagerDuty in the AWS DevOps Agent console:

  1. In the AWS DevOps Agent console, open the Capability Providers page from the side navigation
  2. In the Available providers section, find PagerDuty under Communication and choose Register
AWS DevOps Agent Capability Providers page with PagerDuty listed under Communication and a Register button

Find PagerDuty under Communication and choose Register.

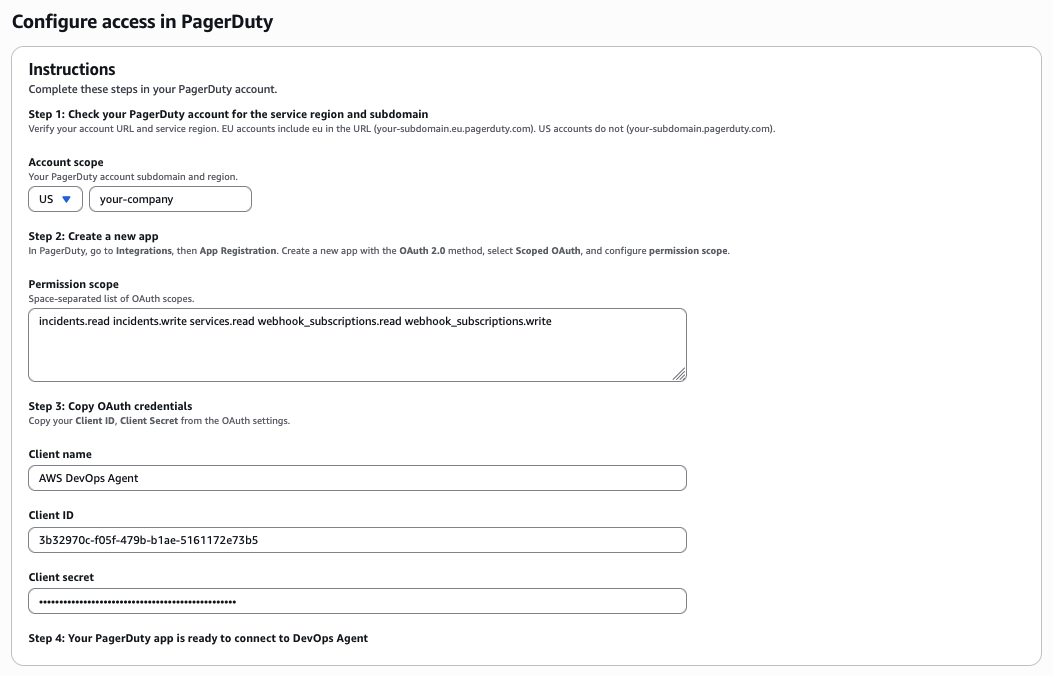
  1. On the Configure access in PagerDuty page, pick your PagerDuty region (US or EU) and enter your PagerDuty subdomain (if your PagerDuty URL is https://your-company.pagerduty.com, the subdomain is your-company)
  2. Paste in the OAuth Client name, Client ID, and Client secret from PagerDuty. Confirm the minimum scopes (incidents.read incidents.write services.read webhook_subscriptions.read webhook_subscriptions.write)
Configure access in PagerDuty form with fields for region, subdomain, OAuth client name, client ID, and client secret

Enter your PagerDuty region, subdomain, and OAuth credentials.

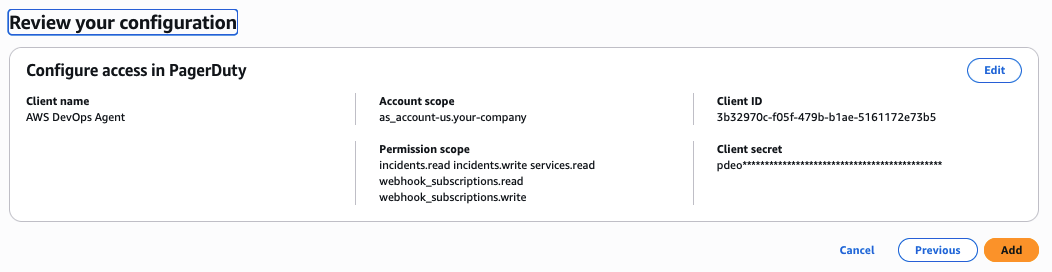
  1. Review the configuration and choose Add
Review screen for the PagerDuty Capability Provider configuration before adding

Review the configuration and choose Add.

Once registration goes through, PagerDuty shows up under the Currently registered section of the Capability Providers page.

Capability Providers page showing PagerDuty under the Currently registered section

PagerDuty appears under Currently registered after registration.

Step 5: Add PagerDuty to your Agent Space

PagerDuty is registered at the account level. Now connect it to the Agent Space that needs it:

  1. In the AWS DevOps Agent console, pick your Agent Space
  2. Open the Capabilities tab
  3. In the Communications section, choose Add
Agent Space Capabilities tab with the Add button in the Communications section

On the Capabilities tab, choose Add in the Communications section.

  1. Select PagerDuty from the list of available providers
Provider selection list with PagerDuty available to add to the Agent Space

Select PagerDuty from the list of available providers.

  1. Choose Associate service

To update OAuth credentials or remove PagerDuty from an Agent Space, see the AWS DevOps Agent documentation.

Step 6: Add PagerDuty MCP Server and configure the agent skill

The Capability Provider from the previous steps handles the event flow. When a PagerDuty incident triggers, AWS DevOps Agent investigates and posts findings back to the originating PagerDuty incident. To let the agent also pull context from PagerDuty during those investigations, you add two things: the PagerDuty MCP server as a custom MCP capability, and an AWS DevOps Agent skill for working with PagerDuty that tells the agent when and how to use it.

Prerequisites:

  • PagerDuty Advance license
  • A PagerDuty User API token (generate one at User Settings > API Access in PagerDuty)

Add the PagerDuty MCP server:

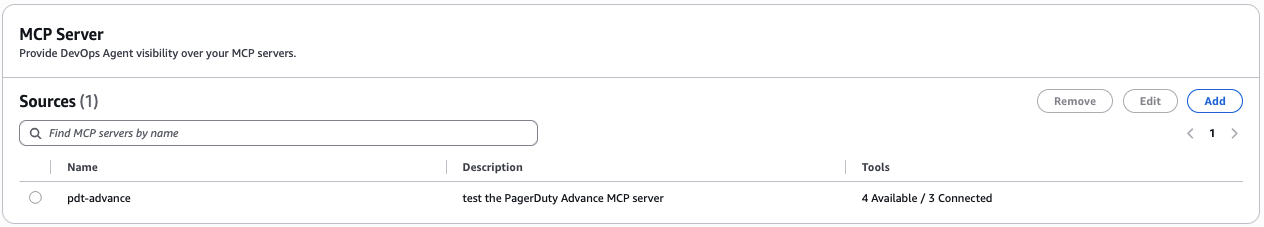
  1. In your Agent Space, go to Capabilities tab > MCP Servers
Agent Space Capabilities tab showing the MCP Servers section

Open the MCP Servers section on the Capabilities tab.

  1. Add a new custom MCP server with the following configuration:
    • Server URL: https://mcp.pagerduty.com/mcp
    • For EU region PagerDuty accounts, use https://mcp.eu.pagerduty.com/mcp instead
    • Authentication: PagerDuty User API token in the format Token token=<your-pagerduty-api-key>
Add custom MCP server form in the AWS DevOps Agent console

Add a new custom MCP server.

MCP server configuration showing the server URL field and PagerDuty User API token authentication field

Configure the server URL and PagerDuty User API token.

Add the AWS DevOps Agent skill for working with PagerDuty:

The MCP server gives the agent access to PagerDuty tools. The skill tells the agent when and how to use them during investigations.

  1. In your Agent Space, choose Operator access to open the web app in a separate browser window
Agent Space console with the Operator access option to open the web app

Choose Operator access to open the web app.

  1. In the Agent Space Operator web app, navigate to Knowledge and the Skills tab, then choose Add skill
AWS DevOps Agent Operator web app Skills page with the Add skill button

On the Skills page, choose Add skill.

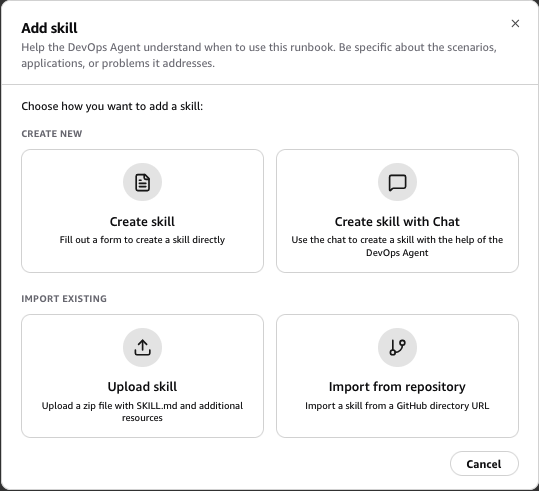
  1. You can select Create skill to create a skill through a wizard, interactively chat with the agent to create a skill, or upload a skill zip file if you already have one
Create skill options showing wizard, interactive chat, and zip upload methods

Choose how to create the skill.

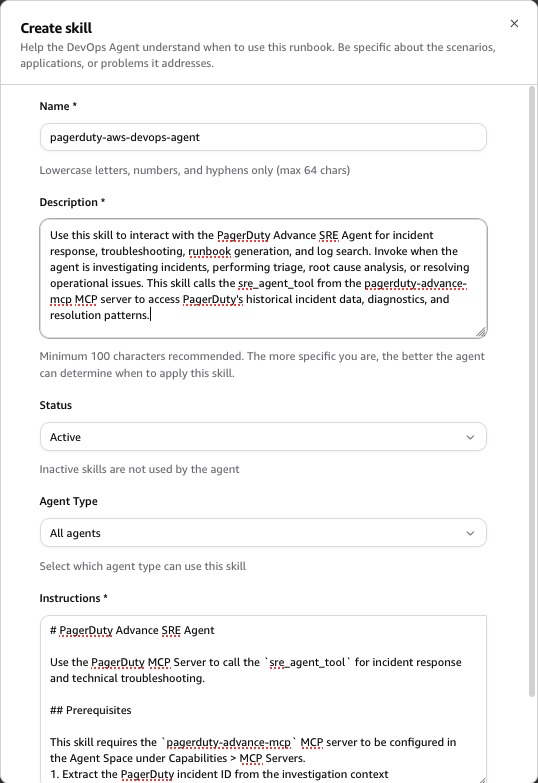
  1. Choose Create skill and fill out the skill instructions from the table below to create a skill
Skill creation form with fields for name, description, status, agent type, and instructions

Fill out the skill instructions.

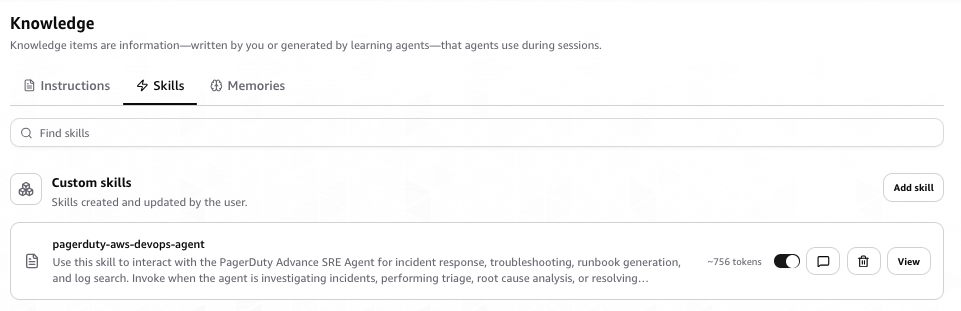
  1. You should see the pagerduty-aws-devops-agent skill added to the AWS DevOps Agent
Skills page showing the pagerduty-aws-devops-agent skill successfully added and active alongside the core skills

The pagerduty-aws-devops-agent skill added to AWS DevOps Agent.

Skill form instructions:

Field Value
Name pagerduty-aws-devops-agent
Description Use this skill to interact with the PagerDuty Advance SRE Agent for incident response, troubleshooting, runbook generation, and log search. Invoke when the agent is investigating incidents, performing triage, root cause analysis, or resolving operational issues. This skill calls the sre_agent_tool from the pagerduty-advance-mcp MCP server to access PagerDuty’s historical incident data, diagnostics, and resolution patterns.
Status Active
Agent Type Generic
Instructions See the skill instructions code block below.

Skill instructions (paste into the Instructions field):

# PagerDuty Advance SRE Agent

Use the PagerDuty MCP Server to call the `sre_agent_tool` for incident response and technical troubleshooting.

## Prerequisites

This skill requires the `pagerduty-advance-mcp` MCP server to be configured in the Agent Space under Capabilities > MCP Servers.

1. Extract the PagerDuty incident ID from the investigation context
2. Call the `sre_agent_tool` from the `pagerduty-advance-mcp` MCP server with:
   - `message`: a natural language question about the incident
   - `incident_id`: the PagerDuty incident ID
3. If follow-up queries are needed, continue calling `sre_agent_tool` with the same `incident_id` and a new `message`. Pass the `session_id` from the previous response to maintain conversation

## Tool Details

- **Tool name:** `sre_agent_tool`
- **MCP Server:** `pagerduty-advance-mcp`
- **Parameters:**
  - `message` (string, required) — natural language question about the incident
  - `incident_id` (string, required) — the PagerDuty incident ID
  - `session_id` (string, optional) — reuse from previous response for conversation continuity

## What the SRE Agent Can Help With

- Active incident analysis, triage, and resolution
- Root cause analysis and technical explanations
- Incident summaries and catch-ups
- Status updates for stakeholders
- Diagnostic checks and remediation recommendations
- Log interpretation and troubleshooting guidance
- Alert trigger analysis and explanations
- Change event analysis and impact assessment
- Playbook and runbook generation
- Past incident correlation and pattern recognition
- Service dependencies and related system analysis
- Real-time incident monitoring and alerting questions

Step 7: Test and validate

Before you call it finished, confirm things work end to end:

  1. Create a test incident in PagerDuty
  2. Confirm AWS DevOps Agent picks up the event and starts an investigation
  3. Watch the investigation move along in the AWS DevOps Agent console or web app
  4. Review the root cause summary, the mitigation plan, and the investigation findings
  5. Verify that root cause analysis and mitigation steps appear on the originating PagerDuty incident record. If you’ve also connected Slack, check that updates land in your configured channel

Start with a limited scope for your initial Agent Space. Focus on a single application or service first. Get comfortable with the integration, tune your configuration, and then expand from there.

Troubleshooting

A handful of things we’ve seen trip people up:

Registration fails with invalid credentials. Double-check that the Client ID and Client secret were copied from the right PagerDuty OAuth 2.0 Scoped OAuth app. Legacy PagerDuty OAuth apps (the ones configured with a redirect URI) aren’t supported. When credentials do need to change, deregister from the Capability Providers page and re-register with the new values, rather than trying to edit in place.

Webhook events don’t trigger an investigation. AWS DevOps Agent only supports PagerDuty V3 webhooks. If your PagerDuty subscription is still on an older webhook version, upgrade to V3. Full details live in Webhooks Overview in the PagerDuty developer documentation.

PagerDuty shows as registered, but isn’t active in an Agent Space. Registering at the account level and adding the provider to an Agent Space are two separate actions. On the Agent Space’s Capabilities tab, check that PagerDuty appears under Communications. If it doesn’t, add it there.

Region or subdomain mismatch. If your PagerDuty account is on the EU service region, make sure you picked EU during registration. The subdomain has to match the first label of your PagerDuty URL exactly (for example, your-company from https://your-company.pagerduty.com).

Conclusion

Most of what happens in the first several minutes of incident response is undifferentiated heavy lifting like opening dashboards, tailing logs, correlating deployments with AWS CloudTrail events. With the native PagerDuty Capability Provider in AWS DevOps Agent, investigations automatically begin by the time you’ve acknowledged your alert, giving your engineers a head start on root cause analysis before responders have finished triaging.

To get started, check out the AWS DevOps Agent documentation or reach out to your PagerDuty or AWS account team.

Resources

About the authors

Shan Kandaswamy

Shan Kandaswamy

Shan is a Senior Partner Solutions Architect specializing in generative AI at AWS, dedicated to solving complex user challenges. He advocates for innovative AI solutions, distributed architecture, and serverless technologies, helping users harness the power of generative AI in their cloud journey. You can reach him on LinkedIn.

Laith Al-Saadoon

Laith Al-Saadoon

Laith Al-Saadoon is a Principal AI Engineer at AWS. He created and launched AWS MCP Servers (30M+ PyPI downloads) and contributes to Strands Agents SDK — AWS’s open-source framework for building AI agents — along with other agentic AI open-source projects like Mem0 and Agno. He drives AWS’s autonomous software development and agentic AI strategy and builds production agentic systems that make agents work for the world’s largest companies. In his personal time, Laith enjoys the outdoors — fishing, photography, drone flights, and hiking with his wife.

Scott Schreckengaust

Scott Schreckengaust

Scott Schreckengaust brings a biomedical engineering degree and decades of deep domain expertise in healthcare and life sciences to emerging technologies and AI. He’s spent his career building—from automating lab workflows and integrating enterprise systems to architecting full-stack software deployments in regulated environments. Now working as an AI engineer, Scott continues what he’s always done best: partner with customers to uncover their scientific and operational challenges, then engineer solutions that scale. His journey from the bench to the cloud reflects a consistent belief: the best technology is invisible—it just works.


Diagnose EKS Node Issues Faster with AWS DevOps Agent and Custom MCP

Post Syndicated from Shyam Kulkarni original https://aws.amazon.com/blogs/devops/diagnose-eks-node-issues-faster-with-aws-devops-agent-and-custom-mcp/

AWS DevOps Agent can investigate a growing range of production incidents autonomously. It diagnoses CrashLoopBackOff failures, traces ConfigMap deletions through audit logs, and correlates Amazon CloudWatch metrics with cluster events — all without human intervention.

But AWS DevOps Agent has a visibility boundary. When the data it needs lives outside its native integrations — on a node’s operating system, inside a third-party monitoring tool, behind a database’s internal diagnostics — the agent stalls. It can describe symptoms, but it can’t reach the evidence needed to identify root causes.

This post shows how to extend AWS DevOps Agent by building a custom Model Context Protocol (MCP) server that bridges that gap. Using a concrete example, we give AWS DevOps Agent structured access to Amazon EKS worker node diagnostics and explain how the same approach applies to data sources the agent can’t natively reach. By the end of this walkthrough, you will have a working MCP server that gives AWS DevOps Agent access to 20+ node-level log sources — providing autonomous investigation capabilities that can assist in root cause analysis compared to manual SSH sessions.

Prerequisites

Before you begin, make sure you have the following:

  • An Amazon EKS cluster with AWS Systems Manager Agent (SSM Agent) running on the worker nodes (included by default on Amazon EKS optimized AMIs)
  • Node.js v18 or later
  • AWS CLI v2
  • AWS CDK v2 installed and bootstrapped in your target account and Region
  • An AWS account with permissions to create IAM roles, Lambda functions, and Amazon S3 buckets
  • Familiarity with Amazon EKS, AWS Systems Manager, and the Model Context Protocol (MCP)

How AWS DevOps Agent discovers custom tools through MCP

MCP is an open standard that defines how AI agents discover and invoke external tools. AWS DevOps Agent supports connecting to custom MCP servers, which means you can expose new capabilities to it without modifying the agent itself. When you connect an MCP server to AWS DevOps Agent, the agent automatically discovers the available tools, understands their schemas, and calls them as part of its investigation workflow. You build and connect the MCP server — the agent handles the rest.

The extensibility model follows three steps: first, identify the data source that AWS DevOps Agent cannot natively access; second, build an MCP server that wraps safe, structured access to that data source; and third, connect the MCP server to AWS DevOps Agent so it can incorporate the new tools into its investigations.

Three design principles make this work. Return structured data, not raw text — pre-index findings with severity levels and stable IDs so the agent can filter, reference, and correlate them. Never give the agent a shell — mediate interactions through a controlled, auditable execution model. Make tools composable — design tool outputs to serve as inputs to other tools, creating a chain of evidence the agent can follow.

Why Amazon EKS node OS visibility matters

AWS DevOps Agent integrates with Amazon EKS to inspect pod status, read container logs, query CloudWatch Container Insights, and correlate cluster events. This covers application crashes, container-level resource exhaustion, and configuration drift.

However, EKS production issues with nodes originate in a layer these tools cannot reach: the node operating system. Artifacts such as iptables rules, full CNI configuration and IPAMD state, route tables, conntrack entries, dmesg kernel messages, containerd runtime logs, sysctl parameters, ENI metadata, and the unfiltered kubelet journal exist exclusively on the node. These artifacts are the primary evidence for diagnosing IP allocation failures, DNS resolution issues, network policy enforcement problems, storage mount timeouts, and node registration failures.

Integrating AWS DevOps Agent with an EKS node diagnostics MCP server

The sample-eks-node-diagnostics-mcp repository (sample-eks-node-diagnostics-mcp repository) demonstrates this pattern. It provides an MCP server that gives AWS DevOps Agent structured access to node-level diagnostic data, backed by AWS Systems Manager (SSM) Automation for safe, auditable execution.

How it works

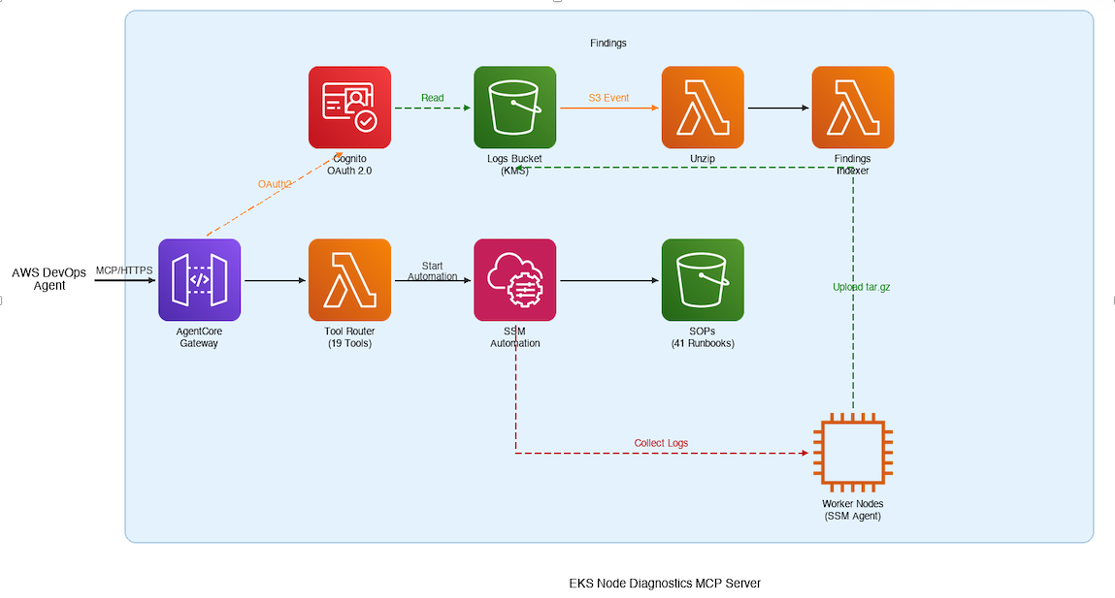
AWS DevOps Agent connects over MCP/HTTPS to AgentCore Gateway, which authenticates via Amazon Cognito OAuth 2.0 and routes tool calls through a Lambda-based Tool Router to SSM Automation. SSM Automation dispatches runbooks to EKS worker nodes running SSM Agent, which upload collected log archives to a KMS-encrypted S3 bucket. An S3 event triggers a Lambda function that extracts and indexes findings for the agent to query.

Figure 1: End-to-end architecture of the EKS Node Diagnostics MCP server. AWS DevOps Agent discovers and invokes 19 tools through AgentCore Gateway, which dispatches SSM Automation runbooks to worker nodes for log collection and uploads results to Amazon S3 for extraction and indexing.

  1. AWS DevOps Agent calls a collect tool with an instance ID.
  2. The MCP server dispatches an SSM Automation execution to the target node, running the AWS-managed AWSSupport-CollectEKSInstanceLogs runbook.
  3. The runbook collects 20+ log sources — kubelet, containerd, iptables, CNI config, route tables, dmesg, sysctl, ENI metadata, IPAMD logs, and more — packages them into an archive, and uploads it to an Amazon S3 bucket where you configure AWS KMS encryption.
  4. A processing pipeline extracts the archive, pre-indexes errors with severity classification and stable finding IDs, and provides the results to you through additional MCP tools.

The server exposes tools for log collection, pre-indexed error retrieval, cross-file search and correlation, structured network diagnostics, and live packet capture. A typical agent workflow chains these together: collect → status → errors → search → correlate → read → summarize, with each step producing outputs that feed into the next.

AWS DevOps Agent does not get a shell on the node. Every interaction is mediated by SSM Automation — an auditable, IAM-controlled, non-interactive execution model.

Connecting through Amazon Bedrock AgentCore Gateway

The reference implementation uses Amazon Bedrock AgentCore Gateway to expose the Lambda-backed MCP server to AWS DevOps Agent. AgentCore Gateway converts Lambda functions into MCP-compatible tools and handles authentication, protocol translation, and tool discovery through a single managed endpoint.

The integration follows three steps:

Step 1: Create an OAuth authorizer with Amazon Cognito. The CDK stack provisions a Cognito User Pool configured for the OAuth 2.0 client credentials flow. This secures inbound access to the gateway — only clients with valid tokens can invoke tools.

Step 2: Create a gateway and register the Lambda as a target. Register the Lambda function that handles tool invocations as a target on the gateway. AgentCore Gateway automatically discovers the tool schemas from the Lambda and makes them available through the MCP protocol. The gateway endpoint becomes the single MCP URL for AWS DevOps Agent.

Step 3: Connect AWS DevOps Agent. Register the MCP server at the account level in the AWS DevOps Agent console, providing the gateway URL and OAuth configuration. Then allowlist the specific tools each Agent Space needs. AWS DevOps Agent authenticates by obtaining a JWT from the Cognito token endpoint using the client credentials grant and passes it as a Bearer token in requests to the gateway URL.

Deploying the MCP server

Deploy the entire stack using AWS CDK :

git clone https://github.com/aws-samples/sample-eks-node-diagnostics-mcp.git
 cd sample-eks-node-diagnostics-mcp
 chmod +x deploy.sh
 ./deploy.sh

The script walks you through cluster selection and node role configuration. Have the following ready before running the script: your target EKS cluster name, the IAM role ARN you attached to your worker nodes, and the AWS Region where your cluster runs. The script outputs your MCP gateway URL, OAuth credentials, and token endpoint — everything you need to configure the connection in AWS DevOps Agent. See the repository README for detailed deployment instructions, CI/CD mode, and prerequisite details.

Seeing it in action

To demonstrate the MCP server’s capabilities, we walk through a realistic node-level failure scenario on a test EKS cluster. We manually inject a fault that blocks pod DNS resolution at the iptables level — an issue that is invisible from kubectl since pods appear Running — then show how AWS DevOps Agent investigates and identifies the root cause using the MCP server’s tools.

Setting up the scenario

Start with an EKS cluster that has a managed node group with SSM Agent running (included by default on Amazon EKS optimized AMIs). Deploy a sample workload to one of the nodes:

kubectl create namespace demo-app

cat <<EOF | kubectl apply -f -
 apiVersion: apps/v1
 kind: Deployment
 metadata:
   name: web-frontend
   namespace: demo-app
 spec:
   replicas: 3
   selector:
     matchLabels:
       app: web-frontend
   template:
     metadata:
       labels:
         app: web-frontend
     spec:
       containers:
       - name: nginx
         image: nginx:latest
         ports:
         - containerPort: 80
 EOF

Identify the node and instance ID where the pods are running:

kubectl get pods -n demo-app -o wide

Injecting the fault

⚠ WARNING: The following commands will disrupt DNS resolution for all pods on the target node. Only run these in a non-production test environment. Do not execute on production nodes.
Connect to the target node using SSM Session Manager and run the following commands to block pod DNS traffic at the iptables level. This simulates a subtle networking issue – pods continue running but can’t resolve DNS, and the root cause is only visible in the node’s iptables rules:

# Block pod traffic to kube-dns ClusterIP — pods run but DNS fails
 # Only affects FORWARD chain (pod traffic), not the node's own DNS
 sudo iptables -I FORWARD -d 10.100.0.10/32 -p udp --dport 53 -j DROP
 sudo iptables -I FORWARD -d 10.100.0.10/32 -p tcp --dport 53 -j DROP

Replace 10.100.0.10 with your cluster’s kube-dns ClusterIP (kubectl get svc kube-dns -n kube-system -o jsonpath=’{.spec.clusterIP}’).

This fault is particularly insidious because kubectl get pods shows all pods in Running state. The applications fail with DNS resolution errors, but there is no Kubernetes event or pod status that points to the cause. The iptables DROP rules targeting the kube-dns ClusterIP exist only in the node’s firewall configuration — a layer that no Kubernetes API call can inspect.

Investigating with AWS DevOps Agent

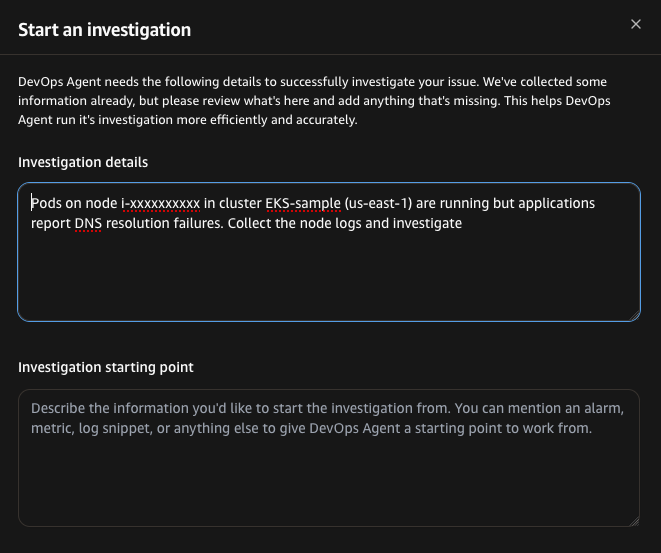
An engineer notices applications reporting DNS failures and asks AWS DevOps Agent to investigate:

“Pods on node i-xxxxxxxxxx in cluster EKS-sample (us-east-1) are running but applications report DNS resolution failures. Collect the node logs and investigate.”

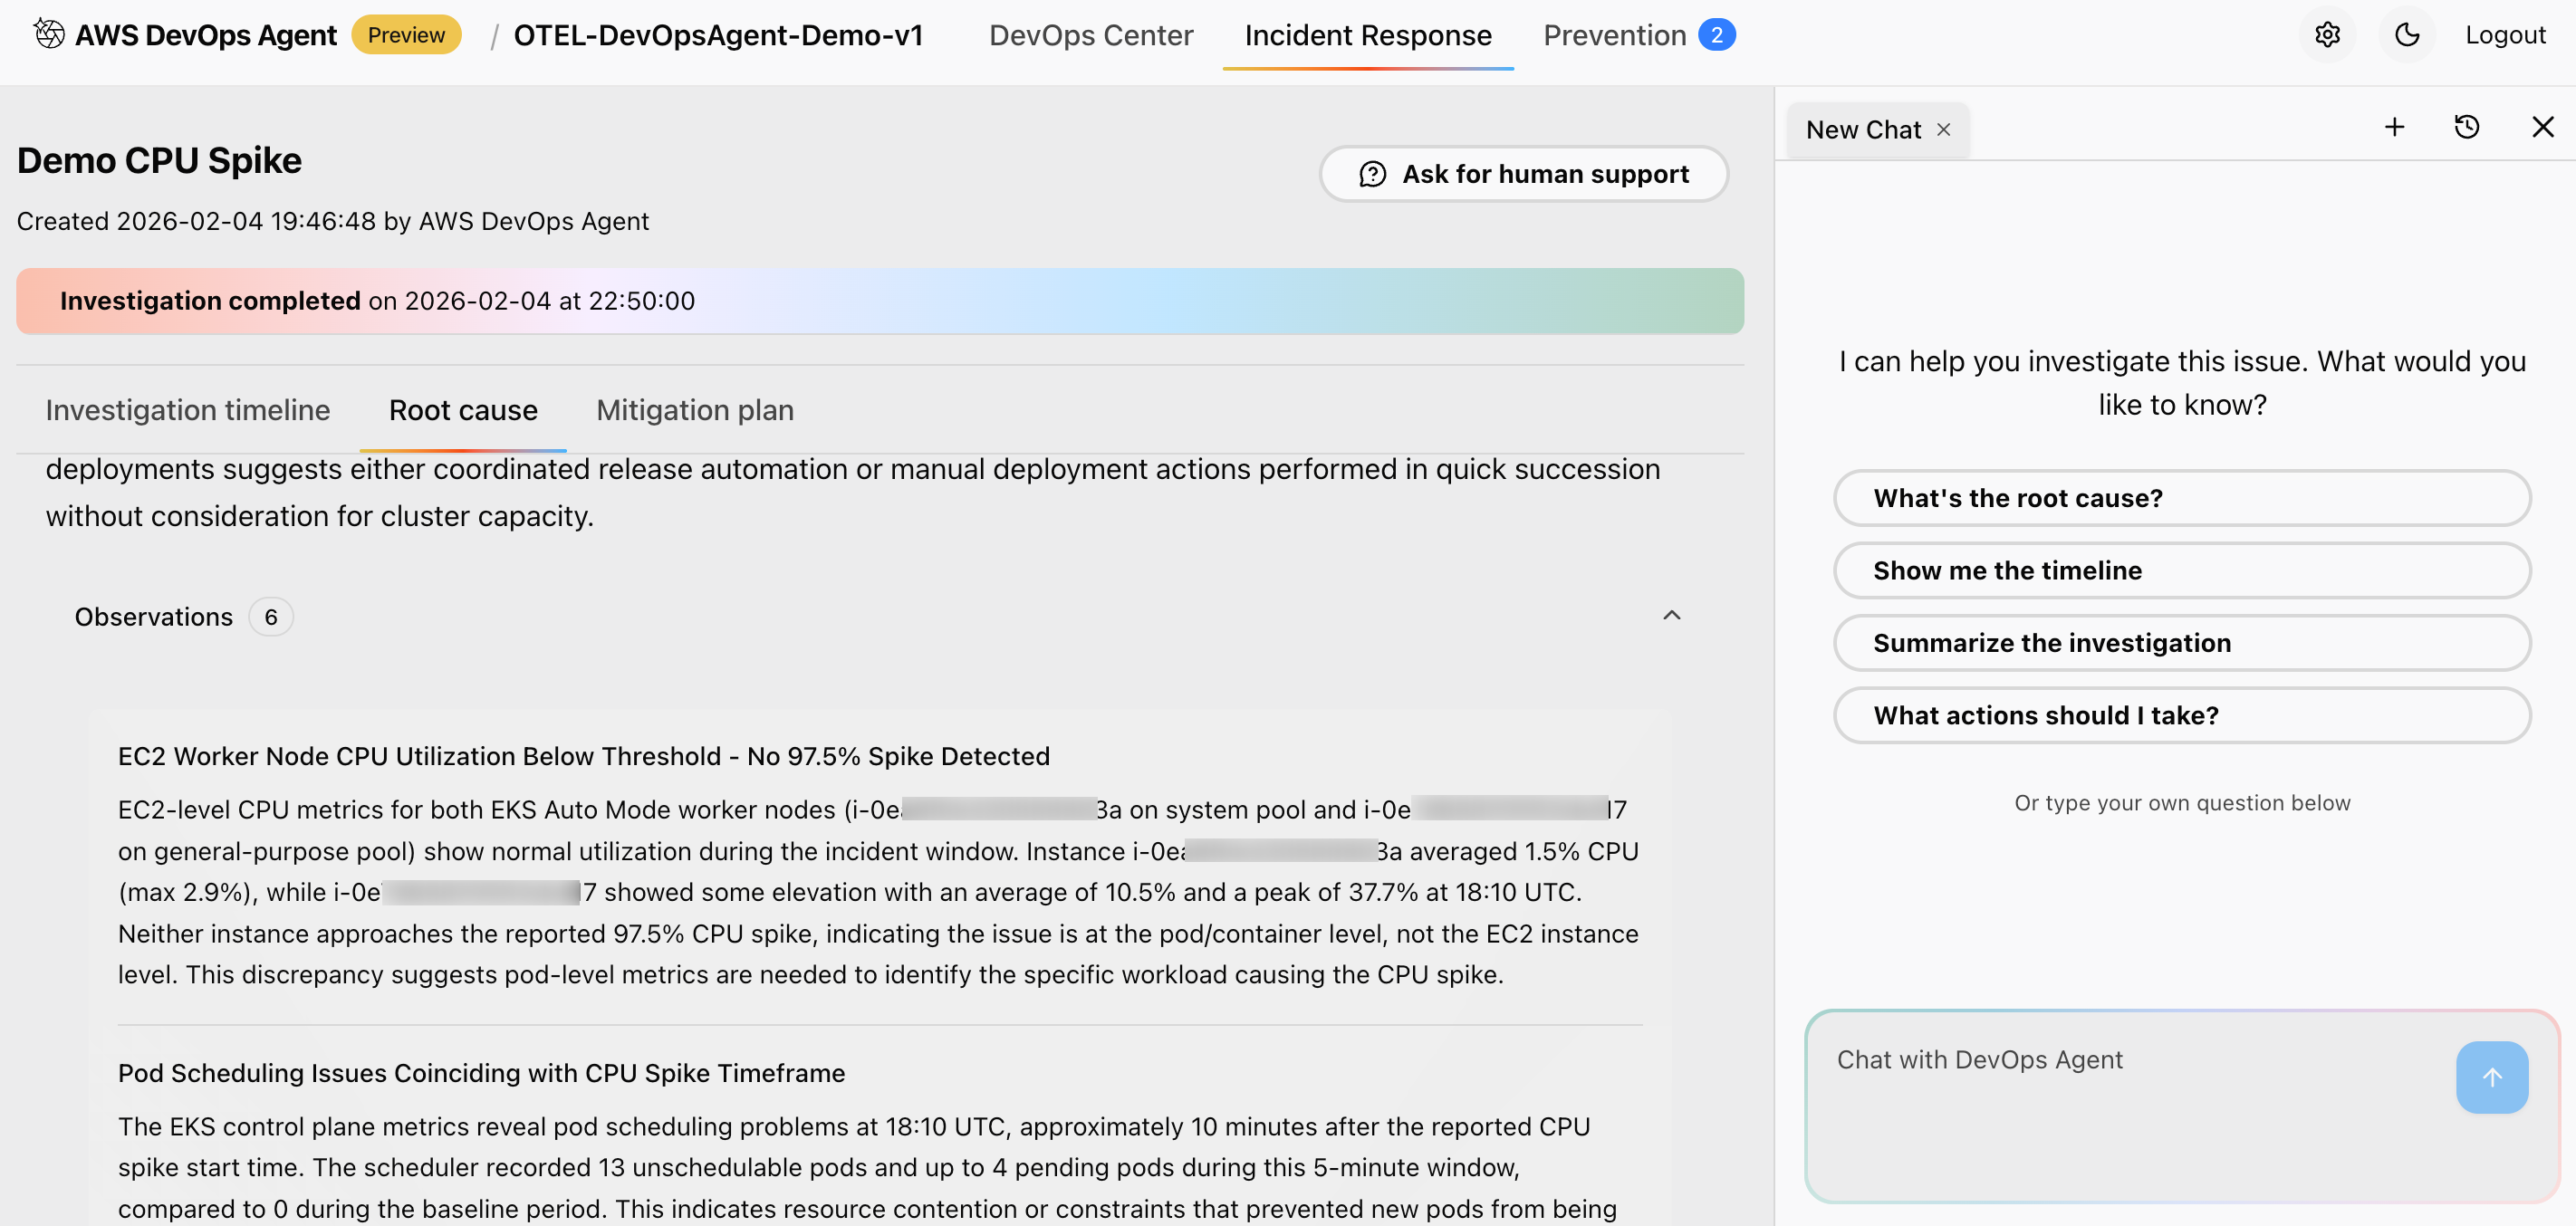
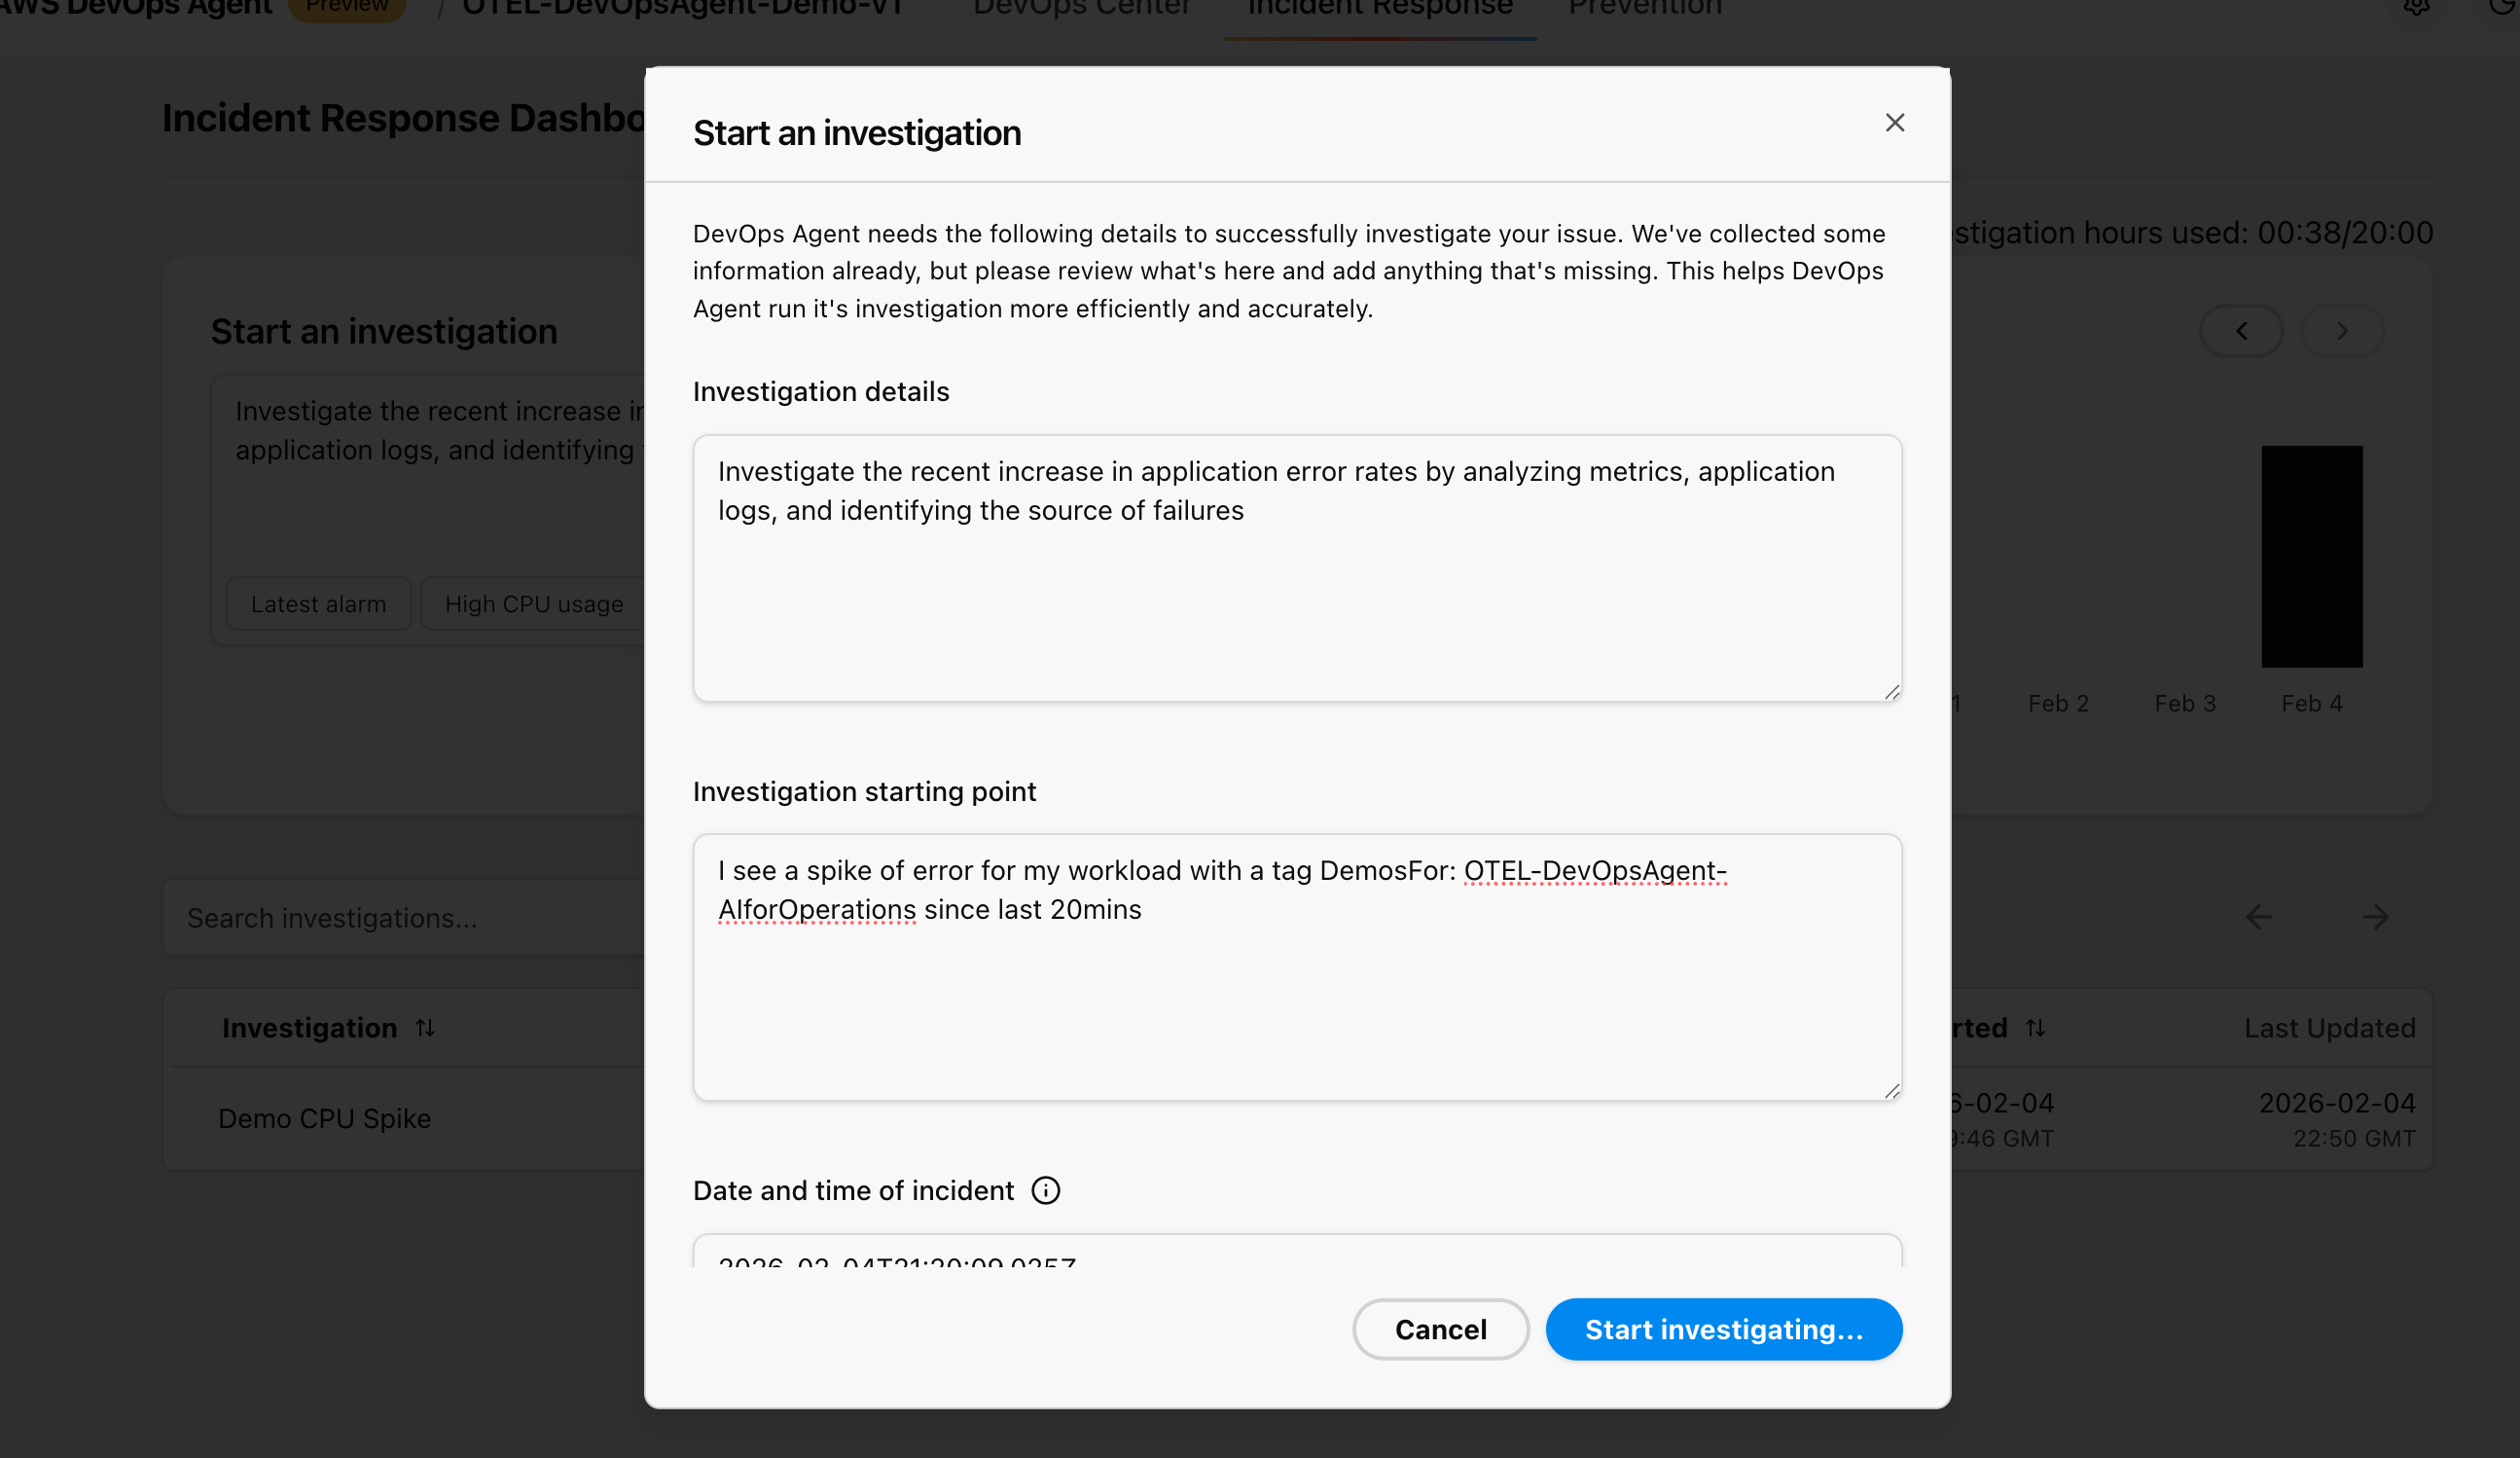
The AWS DevOps Agent "Start an investigation" dialog with the investigation details field populated: "Pods on node i-xxxxxxxxxxxx in cluster EKS-sample (us-east-1) are running but applications report DNS resolution failures. Collect the node logs and investigate." The date and time of incident is set to 2026-03-26T16:55:30.593Z.

Figure 2: Starting an investigation in AWS DevOps Agent. The engineer provides the symptom description and incident timestamp, and the agent autonomously plans and executes the investigation.

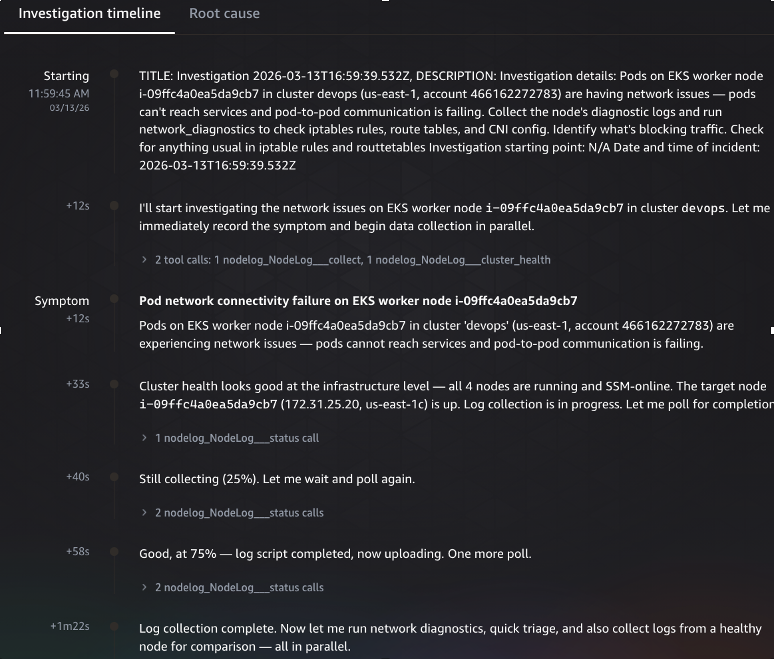
AWS DevOps Agent begins the investigation by recording the symptom and launching two parallel actions: collecting node logs via the nodelog_collect tool and checking cluster health. The cluster health check confirms all four nodes are running and SSM-online. The agent then polls the log collection status, tracking progress from 25% through 75% to completion. Once collection finishes, the agent fans out into parallel workstreams — running network diagnostics, performing quick triage, and collecting logs from a healthy node for comparison.

The investigation timeline progresses from "Starting" at 11:59:45 AM through symptom identification at +12 seconds, cluster health check at +33 seconds confirming all four nodes are running, log collection polling at 25% and 75%, to log collection complete at +1 minute 22 seconds. The agent then launches parallel network diagnostics, quick triage, and healthy node comparison.

Figure 3: Investigation timeline showing the initial data collection phase. The agent identifies the symptom, confirms cluster health, collects node logs via SSM Automation, polls for completion, and launches parallel diagnostic workstreams.

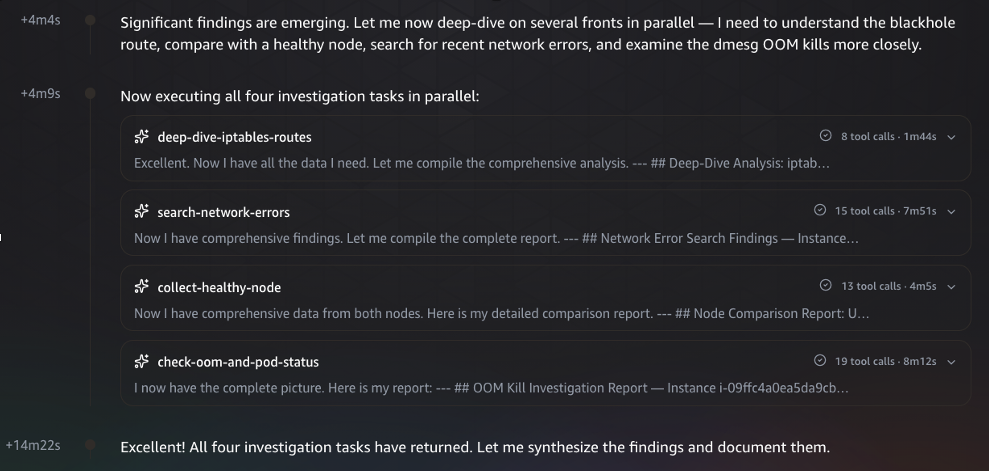
With the initial data collected, the agent launches four parallel investigation tasks to maximize coverage and minimize time-to-root-cause: (1) deep-dive-iptables-routes examines the node’s firewall rules and routing table in detail, completing in 1 minute 44 seconds across 8 tool calls; (2) search-network-errors scans the collected logs for network-related error patterns, running 15 tool calls over 7 minutes 51 seconds; (3) collect-healthy-node gathers the same diagnostics from a known-good node for comparison, taking 13 tool calls over 4 minutes 55 seconds; (4) check-oom-and-pod-status investigates kernel OOM kills and pod health, executing 19 tool calls over 8 minutes 12 seconds. Each task produces a structured report that feeds into the final synthesis.

Four parallel investigation tasks execute concurrently: deep-dive-iptables-routes (8 tool calls, 1 minute 44 seconds), search-network-errors (15 tool calls, 7 minutes 51 seconds), collect-healthy-node (13 tool calls, 4 minutes 5 seconds), and check-oom-and-pod-status (19 tool calls, 8 minutes 12 seconds). At +14 minutes 22 seconds, all four tasks complete and the agent begins synthesizing findings.

Figure 4: Parallel investigation phase. The agent runs four concurrent deep-dive tasks — iptables/route analysis, network error search, healthy node comparison, and OOM/pod status check — then synthesizes the findings into a unified report.

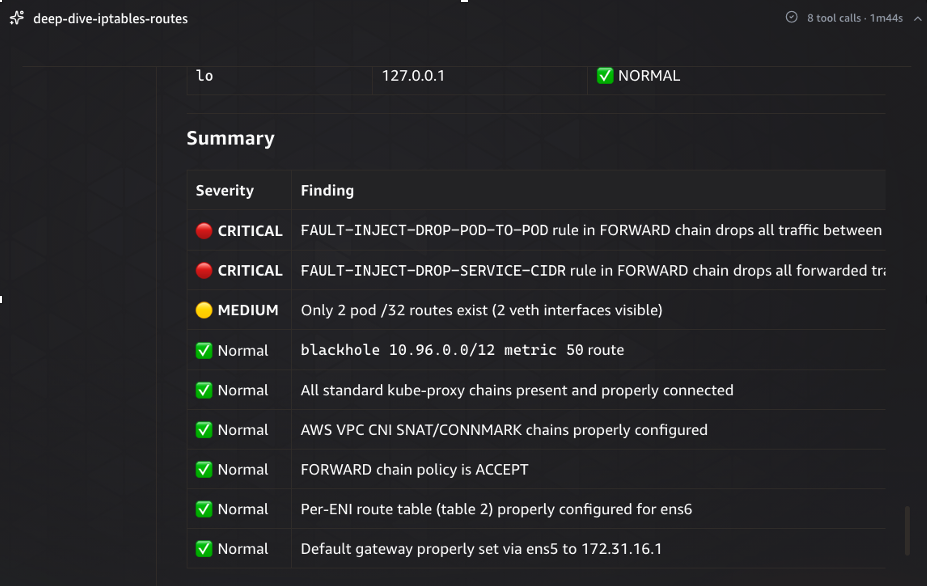
The iptables and route table deep-dive reveals the root cause. The agent identifies two CRITICAL findings: a FAULT-INJECT-DROP-POD-TO-POD rule in the FORWARD chain that drops inter-pod traffic, and a FAULT-INJECT-DROP-SERVICE-CIDR rule that drops forwarded traffic to the service CIDR range. It also flags a MEDIUM-severity finding — a blackhole route for 10.96.0.0/12 (the Kubernetes service CIDR) that does not exist on healthy nodes. The remaining checks come back normal: kube-proxy chains are intact, AWS VPC CNI SNAT/CONNMARK chains are properly configured, and the default gateway and ENI route tables are correct. This structured severity classification allows the agent to immediately focus on the critical items.

A severity-classified findings summary table from the deep-dive-iptables-routes task. Two CRITICAL findings: a FAULT-INJECT-DROP-POD-TO-POD rule and a FAULT-INJECT-DROP-SERVICE-CIDR rule, both in the FORWARD chain. One MEDIUM finding about limited pod /32 routes. Six Normal findings confirm kube-proxy chains, AWS VPC CNI SNAT/CONNMARK chains, FORWARD chain policy, per-ENI route table, and default gateway are all properly configured.

Figure 5: Deep-dive findings from the iptables and route table analysis. Two CRITICAL fault-injection DROP rules in the FORWARD chain are identified as the primary issue, while standard networking components — kube-proxy, VPC CNI, and routing — check normal.

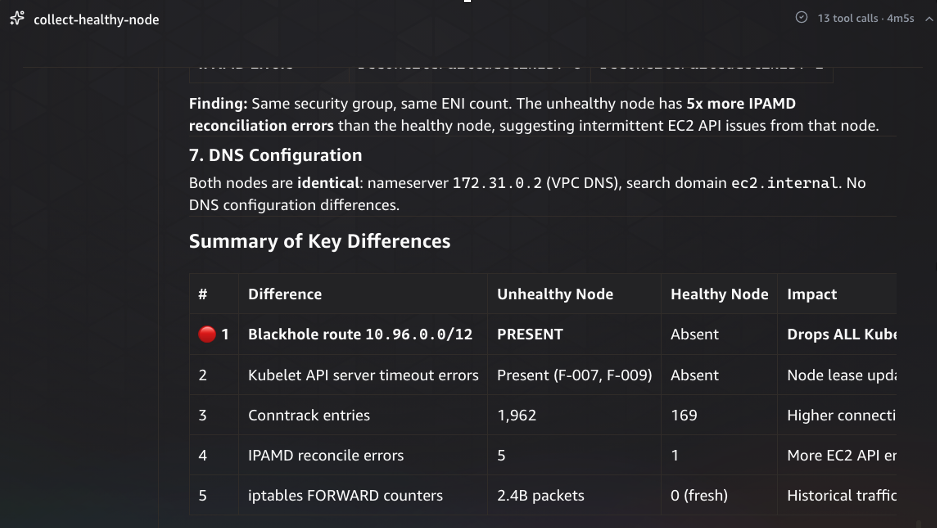
The healthy node comparison confirms the diagnosis. The agent compares the unhealthy node against a known-good node across seven dimensions: security groups, ENI count, DNS configuration, iptables rules, route tables, conntrack entries, and IPAMD state. The key differences are definitive: the blackhole route for 10.96.0.0/12 exists only on the unhealthy node, kubelet API server timeout errors appear only on the unhealthy node, conntrack entries are 12x higher (1,962 vs 169), and IPAMD reconciliation errors are 5x more frequent. The iptables FORWARD chain counters show 2.4 billion packets processed on the unhealthy node versus zero on the freshly-started healthy node — confirming sustained traffic disruption.

A comparison table titled "Summary of Key Differences" between the unhealthy and healthy nodes. Five differences are listed: a blackhole route for 10.96.0.0/12 present only on the unhealthy node, kubelet API server timeout errors present only on the unhealthy node, conntrack entries at 1,962 versus 169, IPAMD reconcile errors at 5 versus 1, and iptables FORWARD counters at 2.4 billion packets versus 0 on the fresh healthy node. DNS configuration is identical on both nodes.

Figure 6: Healthy node comparison confirming the diagnosis. The agent compares diagnostics across both nodes and identifies five key differences — the blackhole route, elevated conntrack entries, and high FORWARD chain packet counts exist only on the affected node.

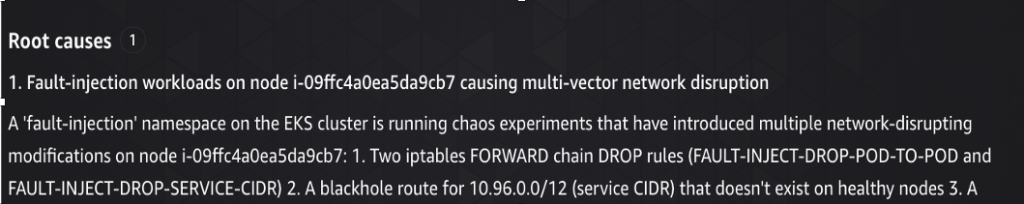
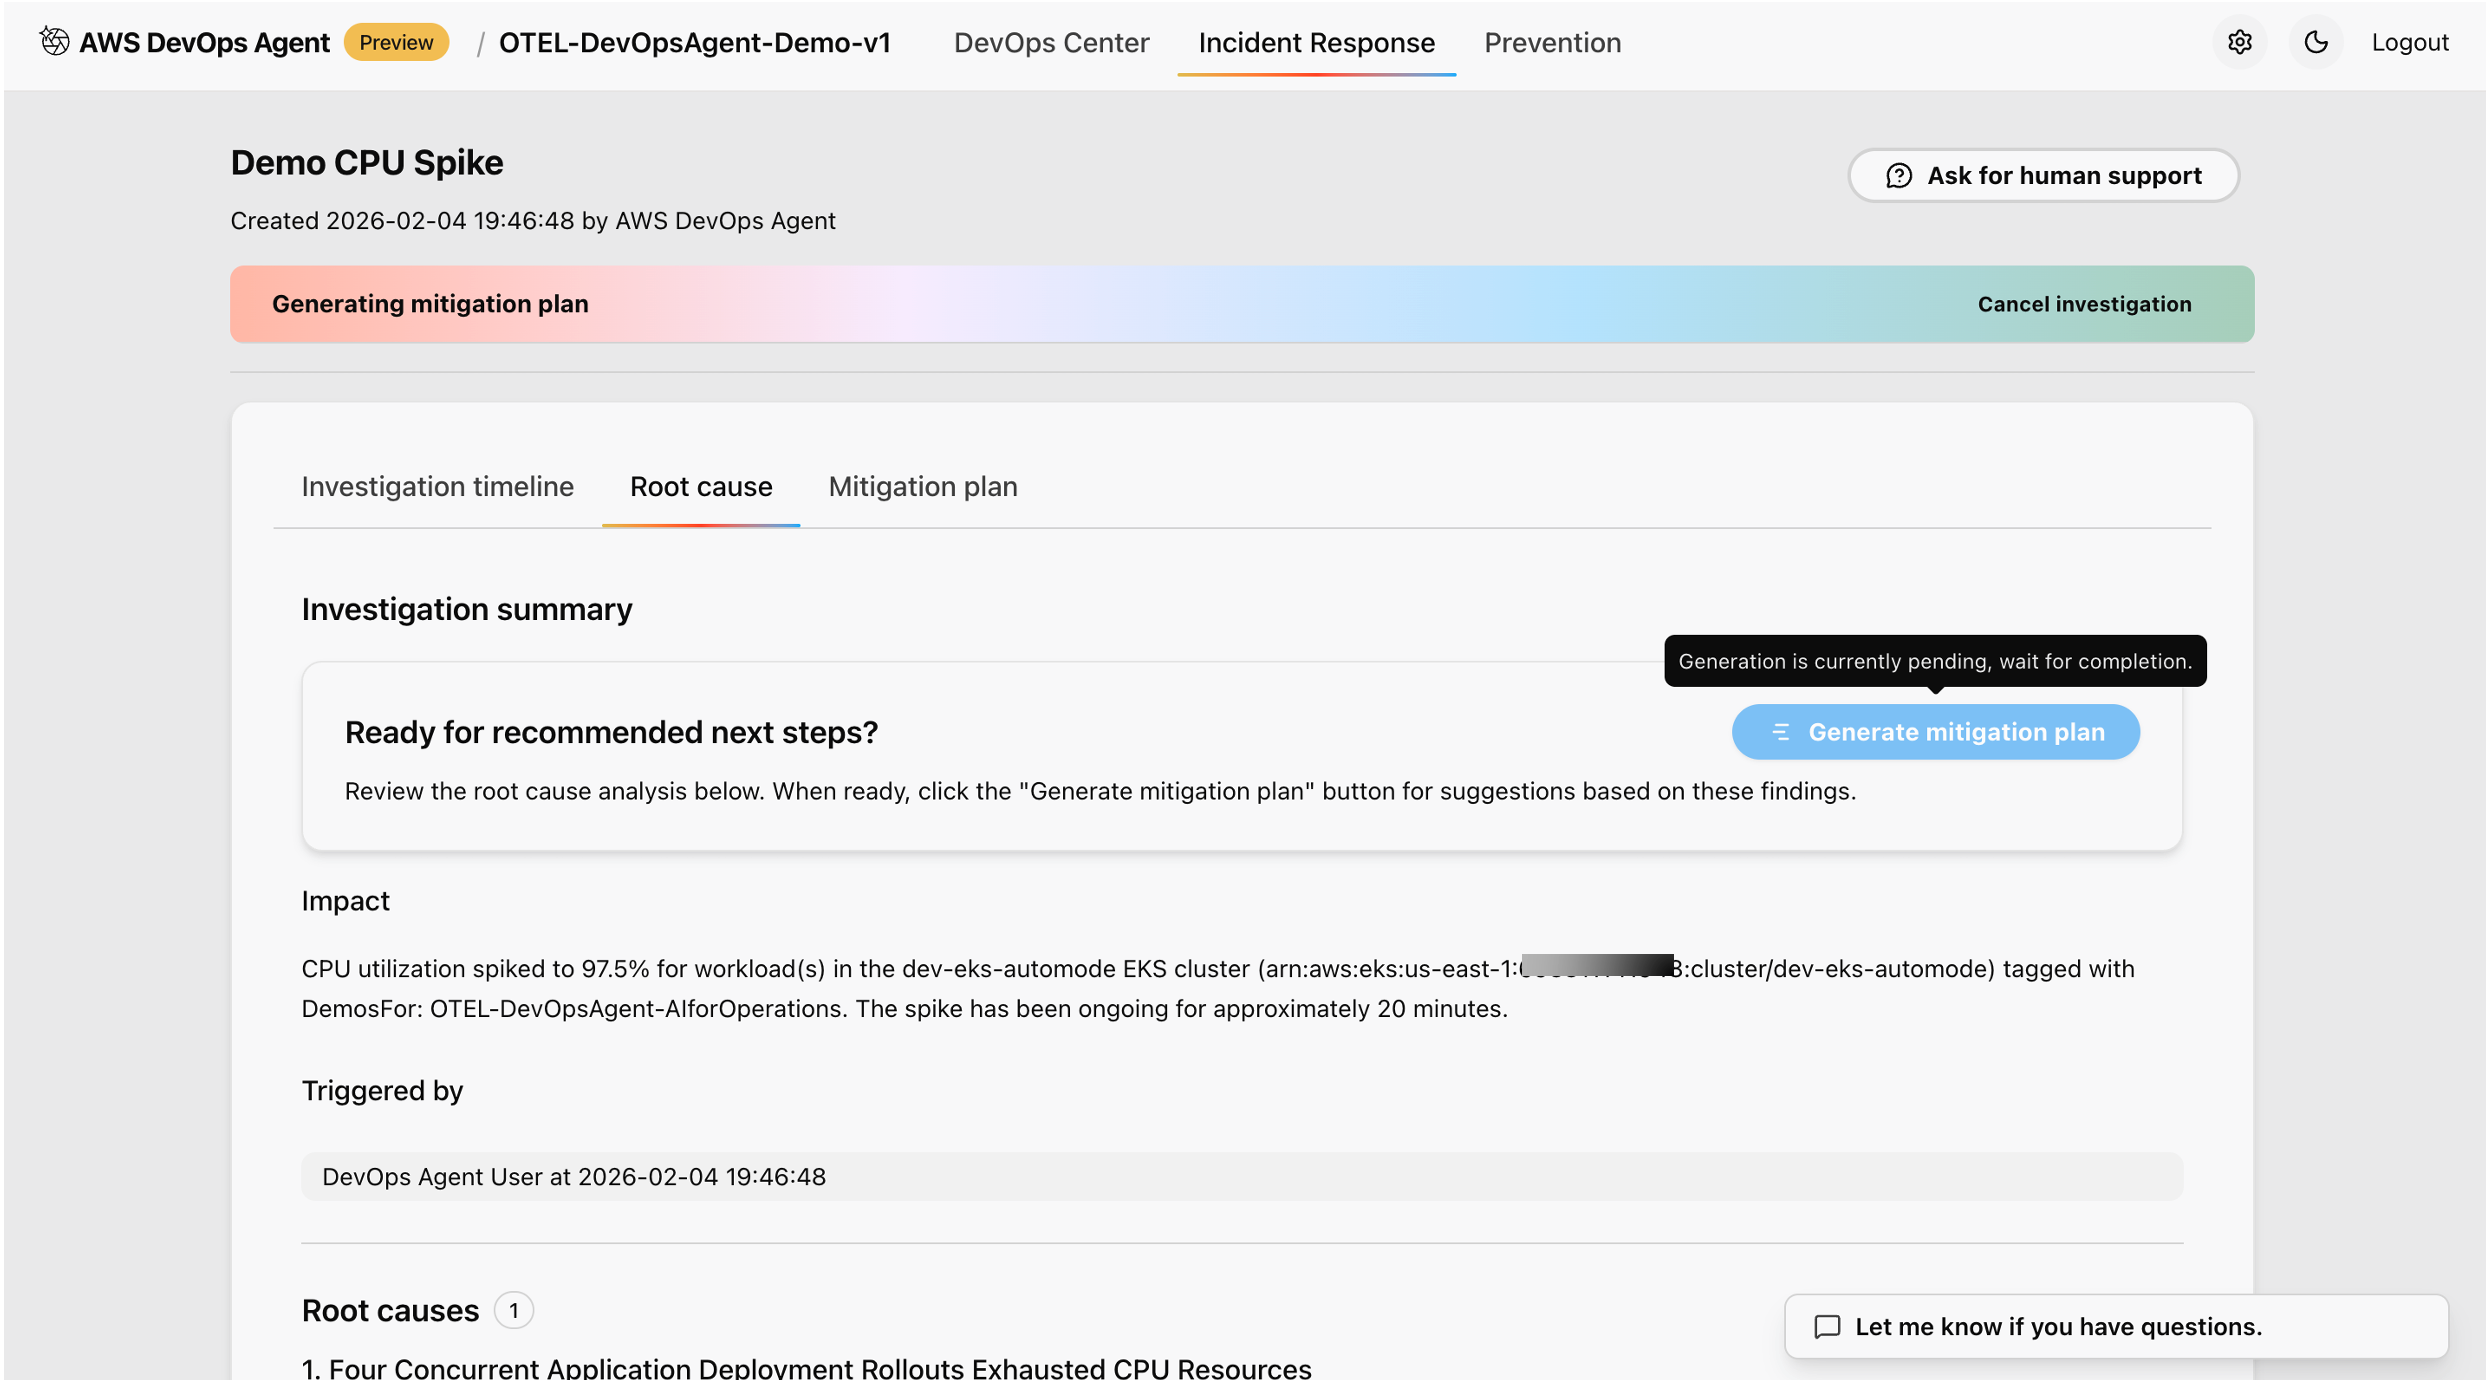
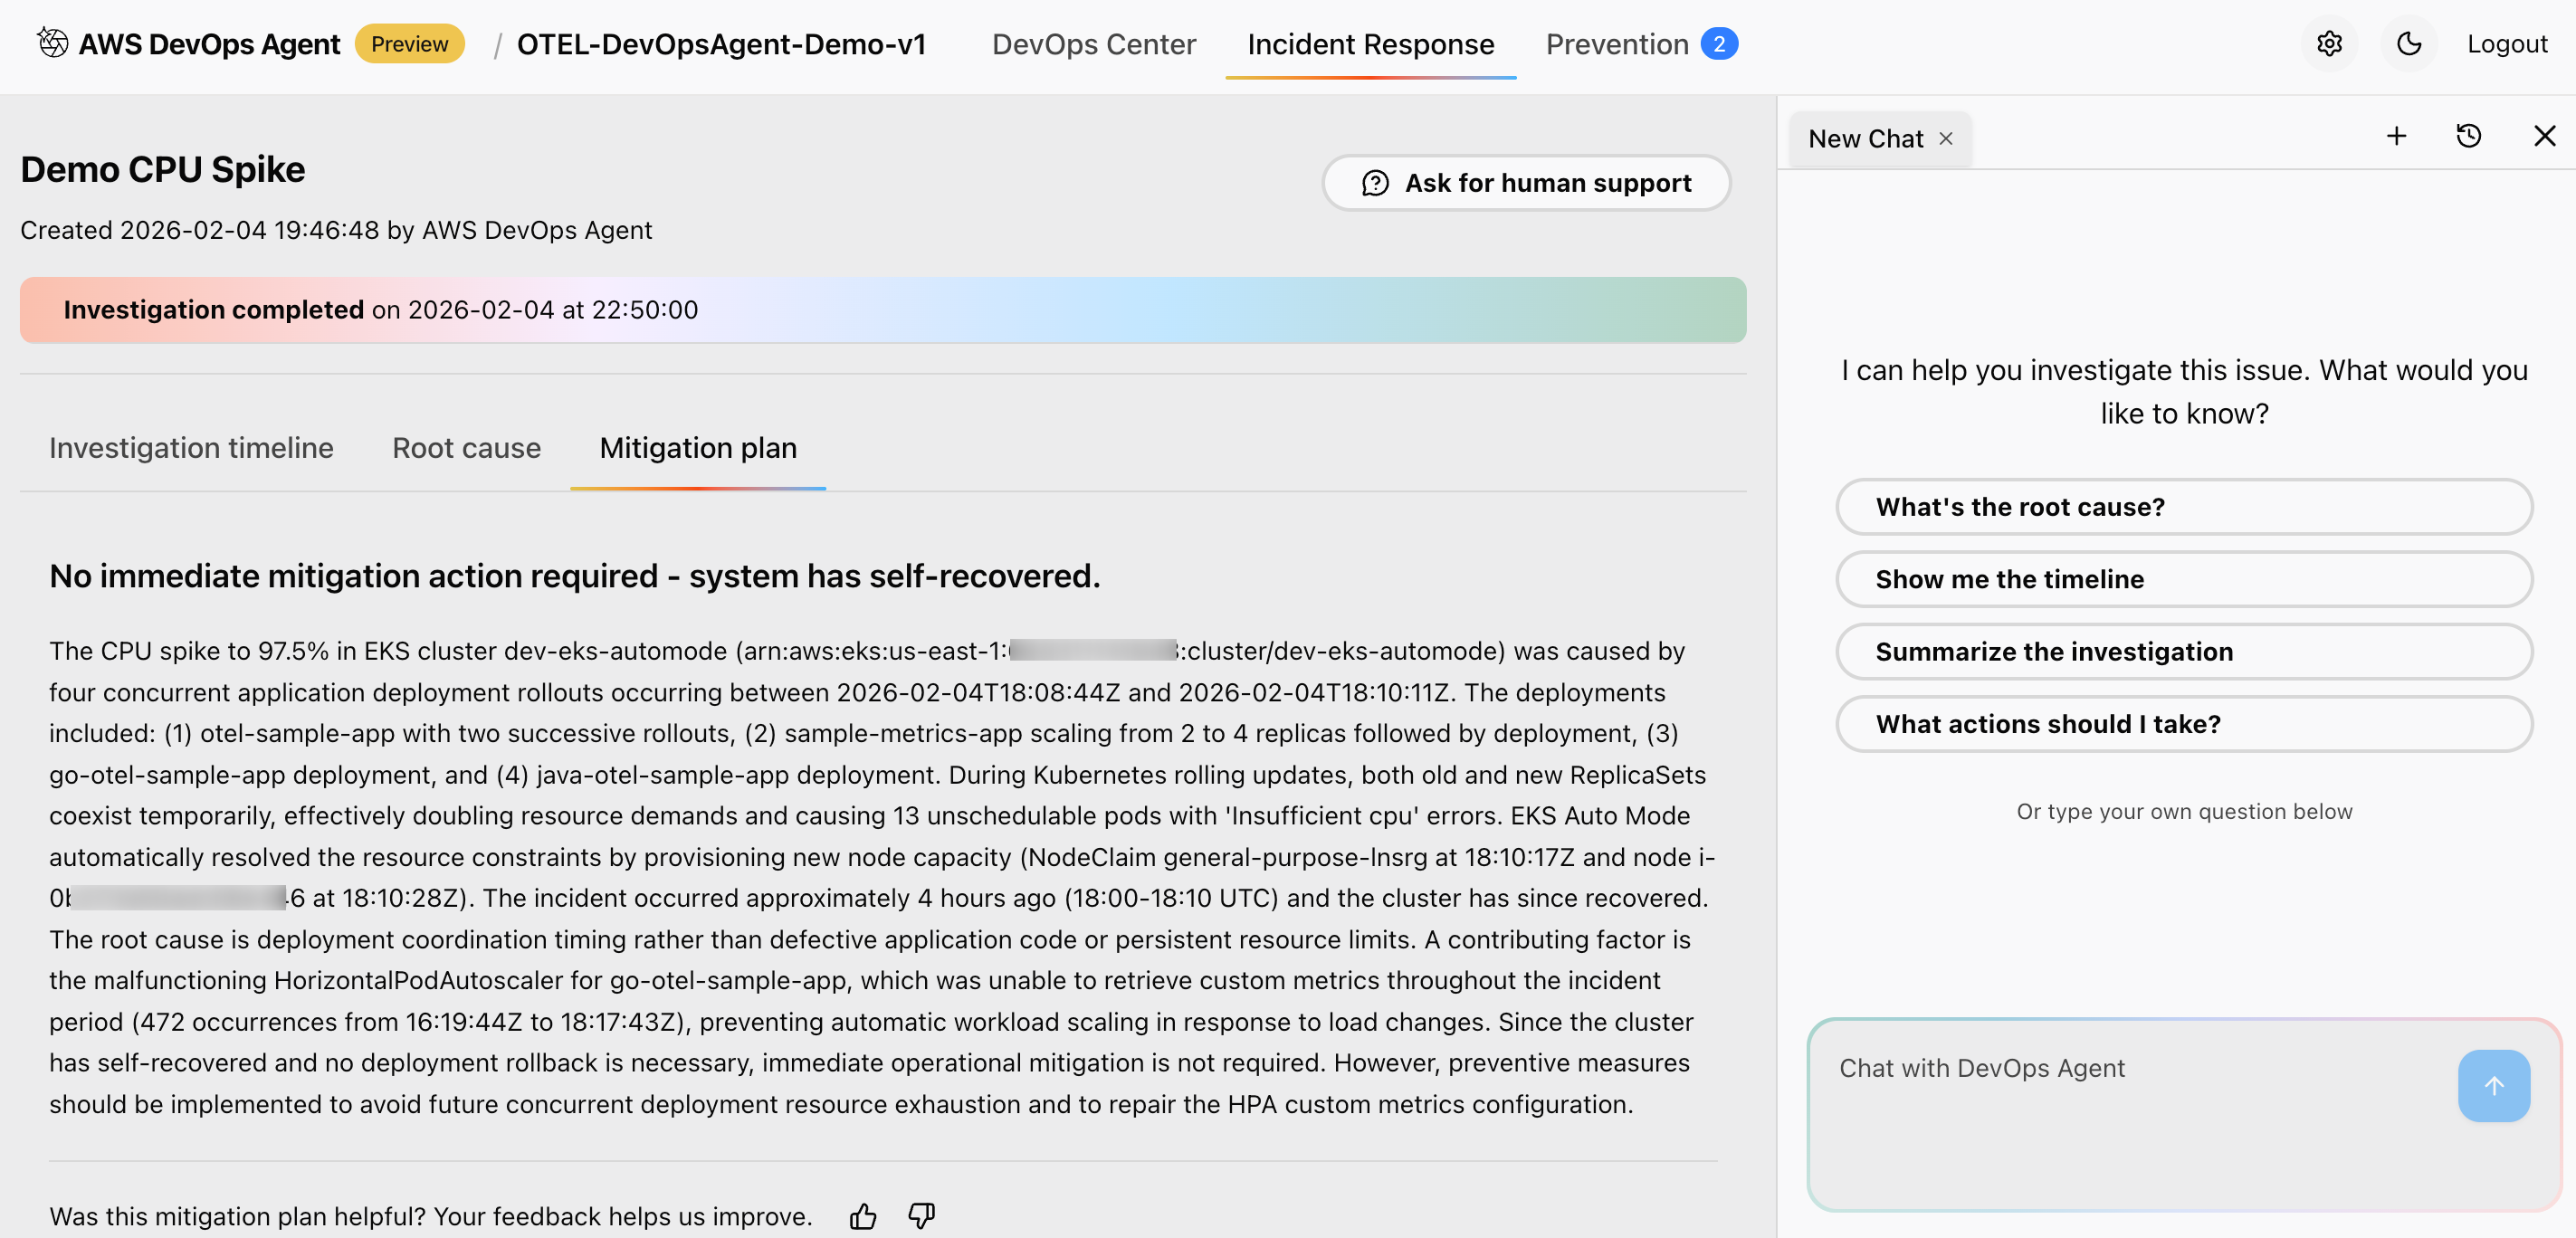
The agent synthesizes the findings into a definitive root cause determination. It identifies a fault-injection namespace on the EKS cluster that is running chaos experiments, introducing three specific network-disrupting modifications on the target node: (1) a FAULT-INJECT-DROP-POD-TO-POD iptables rule in the FORWARD chain that drops inter-pod traffic, (2) a FAULT-INJECT-DROP-SERVICE-CIDR rule that drops forwarded traffic to the Kubernetes service CIDR, and (3) a blackhole route for 10.96.0.0/12 that does not exist on healthy nodes. Together, these three modifications create a multi-vector network disruption — pods appear Running but cannot communicate with each other or reach Kubernetes services, including kube-dns.

The Root causes panel identifies one root cause: "Fault-injection workloads on node i-09ffc4a0ea5da9cb7 causing multi-vector network disruption." The explanation states that a fault-injection namespace is running chaos experiments that introduced two iptables FORWARD chain DROP rules (FAULT-INJECT-DROP-POD-TO-POD and FAULT-INJECT-DROP-SERVICE-CIDR) and a blackhole route for 10.96.0.0/12 that does not exist on healthy nodes.

Figure 7: Root cause determination. The agent traces the multi-vector network disruption to three fault-injection modifications — two iptables DROP rules and a blackhole route — deployed by a chaos experiment namespace on the target node.

Cleaning up the fault

To restore the node after the demo, connect via SSM Session Manager and run:

sudo iptables -D FORWARD -d 10.100.0.10/32 -p udp --dport 53 -j DROP
sudo iptables -D FORWARD -d 10.100.0.10/32 -p tcp --dport 53 -j DROP

Extending this pattern to other data sources

The EKS node diagnostics use case demonstrates the pattern, but the architecture generalizes to systems where the SSM Agent is running and you can define an SSM Automation runbook to collect the data you need.

For example, an EC2 instance with SSM Agent can use this same approach — collect OS-level logs, network configuration, package state, or application diagnostics through a custom or pre-built SSM Automation runbook, upload results to S3, and expose them through MCP tools. The same applies to ECS container instances (Docker daemon logs, ECS agent state, iptables), on-premises servers registered via SSM Hybrid Activations, or managed nodes in your fleet.

The pattern also extends beyond SSM-managed hosts. Network devices can be reached through API calls to their management planes, databases through read-only diagnostic queries, and third-party APM tools through vendor API integrations. In each case, the same three-step approach holds: identify the unreachable data, build an MCP server that wraps safe access to it, and connect it to AWS DevOps Agent.

When to use this approach
This pattern works well for incident response where diagnostic data lives outside AWS DevOps Agent’s native reach, fleet-wide triage where manual access to individual systems is impractical, and cross-source correlation where evidence spans multiple log sources.

It is not a replacement for continuous monitoring (use CloudWatch Container Insights or Prometheus for real-time alerting), log shipping (if you have compliance requirements for continuous retention), or native integrations where the agent already has access to the data source.

The reference implementation requires SSM Agent running on the nodes with appropriate IAM permissions. It is a proof of concept — validate it in non-production environments before using it with production workloads.

Clean up

Cost considerations: This solution uses AWS Lambda, Amazon S3, AWS KMS, Amazon Cognito, and Amazon Bedrock AgentCore Gateway. Costs vary based on usage. Lambda charges apply per invocation and duration. S3 charges apply for log storage. KMS charges a per-key monthly fee plus per-request charges. Cognito charges per monthly active user. AgentCore Gateway pricing is based on API calls. For current pricing details, see the AWS Pricing page for each service. To minimize costs during evaluation, delete the stack when not in use.

Remove the deployed resources by running cdk destroy from the repository root. The S3 log bucket uses a RETAIN removal policy — delete it manually after stack destruction if needed.

Conclusion

MCP provides a standardized extensibility mechanism that lets you bridge visibility gaps in AWS DevOps Agent without modifying the agent itself. The pattern is straightforward: identify the unreachable data source, build an MCP server that wraps safe and structured access to it, and connect it to AWS DevOps Agent through Amazon Bedrock AgentCore Gateway. The agent handles the reasoning. The MCP server handles the data access.

To get started:

  • Deploy the reference implementation (sample-eks-node-diagnostics-mcp repository) in a non-production environment.
  • Review the MCP specification (MCP specification).
  • Explore the Amazon EKS troubleshooting documentation (Amazon EKS troubleshooting documentation).
  • Connect custom MCP servers to AWS DevOps Agent — see the Connecting MCP Servers guide in the AWS DevOps Agent documentation.
  • Set up AgentCore Gateway — see the Amazon Bedrock AgentCore Gateway quick start guide.

About the author

Shyam Kulkarni

Shyam Kulkarni

Shyam Kulkarni is a Sr. Technical Account Manager at AWS, where he helps enterprise customers design and implement cloud-native architectures with a focus on container orchestration, platform engineering, and observability at scale. He advises organizations on strategic modernization initiatives and is passionate about architecting AI-native systems, including agentic AI platforms and scalable AI infrastructure. Outside of work, Shyam is an avid travel and landscape photographer who enjoys exploring new destinations and capturing dramatic natural scenery. He’s also an enthusiastic home cook and baker who loves experimenting with new recipes, flavors, and techniques in the kitchen. When not behind a camera or in the kitchen, you’ll find him hiking remote trails.

How AWS DevOps Agent uses multi-agent reasoning to find root causes

Post Syndicated from Harish Mandhadi original https://aws.amazon.com/blogs/devops/how-aws-devops-agent-uses-multi-agent-reasoning-to-find-root-causes/

Confirmation bias is one of the most common reasons incident investigations take longer than they should. An on-call engineer gets alerted, forms a theory based on initial triage and experience, finds one piece of supporting evidence, and stops looking. The actual root cause — buried in a different service, a different signal, a different time window — goes undiscovered for longer than it should.

Modern distributed systems don’t lack telemetry. They lack reasoning — the ability to generate multiple explanations simultaneously, actively challenge each one, and converge on the true cause only when the evidence conclusively supports it.

AWS DevOps Agent, an autonomous agent, solves this with a multi-agent architecture that decomposes incident operations into specialized capabilities — each optimized for a different operational priority. But investigating an incident effectively requires starting with broader architectural context — which resources exist, how they relate to each other, and how they change with every deployment. That architectural understanding is what makes the difference between an agent that searches blindly through telemetry and one that reasons about your system.

In this post, we go inside the investigation lifecycle to explain how AWS DevOps Agent reasons through complex incidents — from the topology foundation that gives it architectural awareness, through autonomous triage and deep multi-hypothesis investigation, to the learning loop that prevents future incidents. Understanding how these capabilities connect is what turns the AWS DevOps Agent from a black box into a trusted member of your on-call rotation.

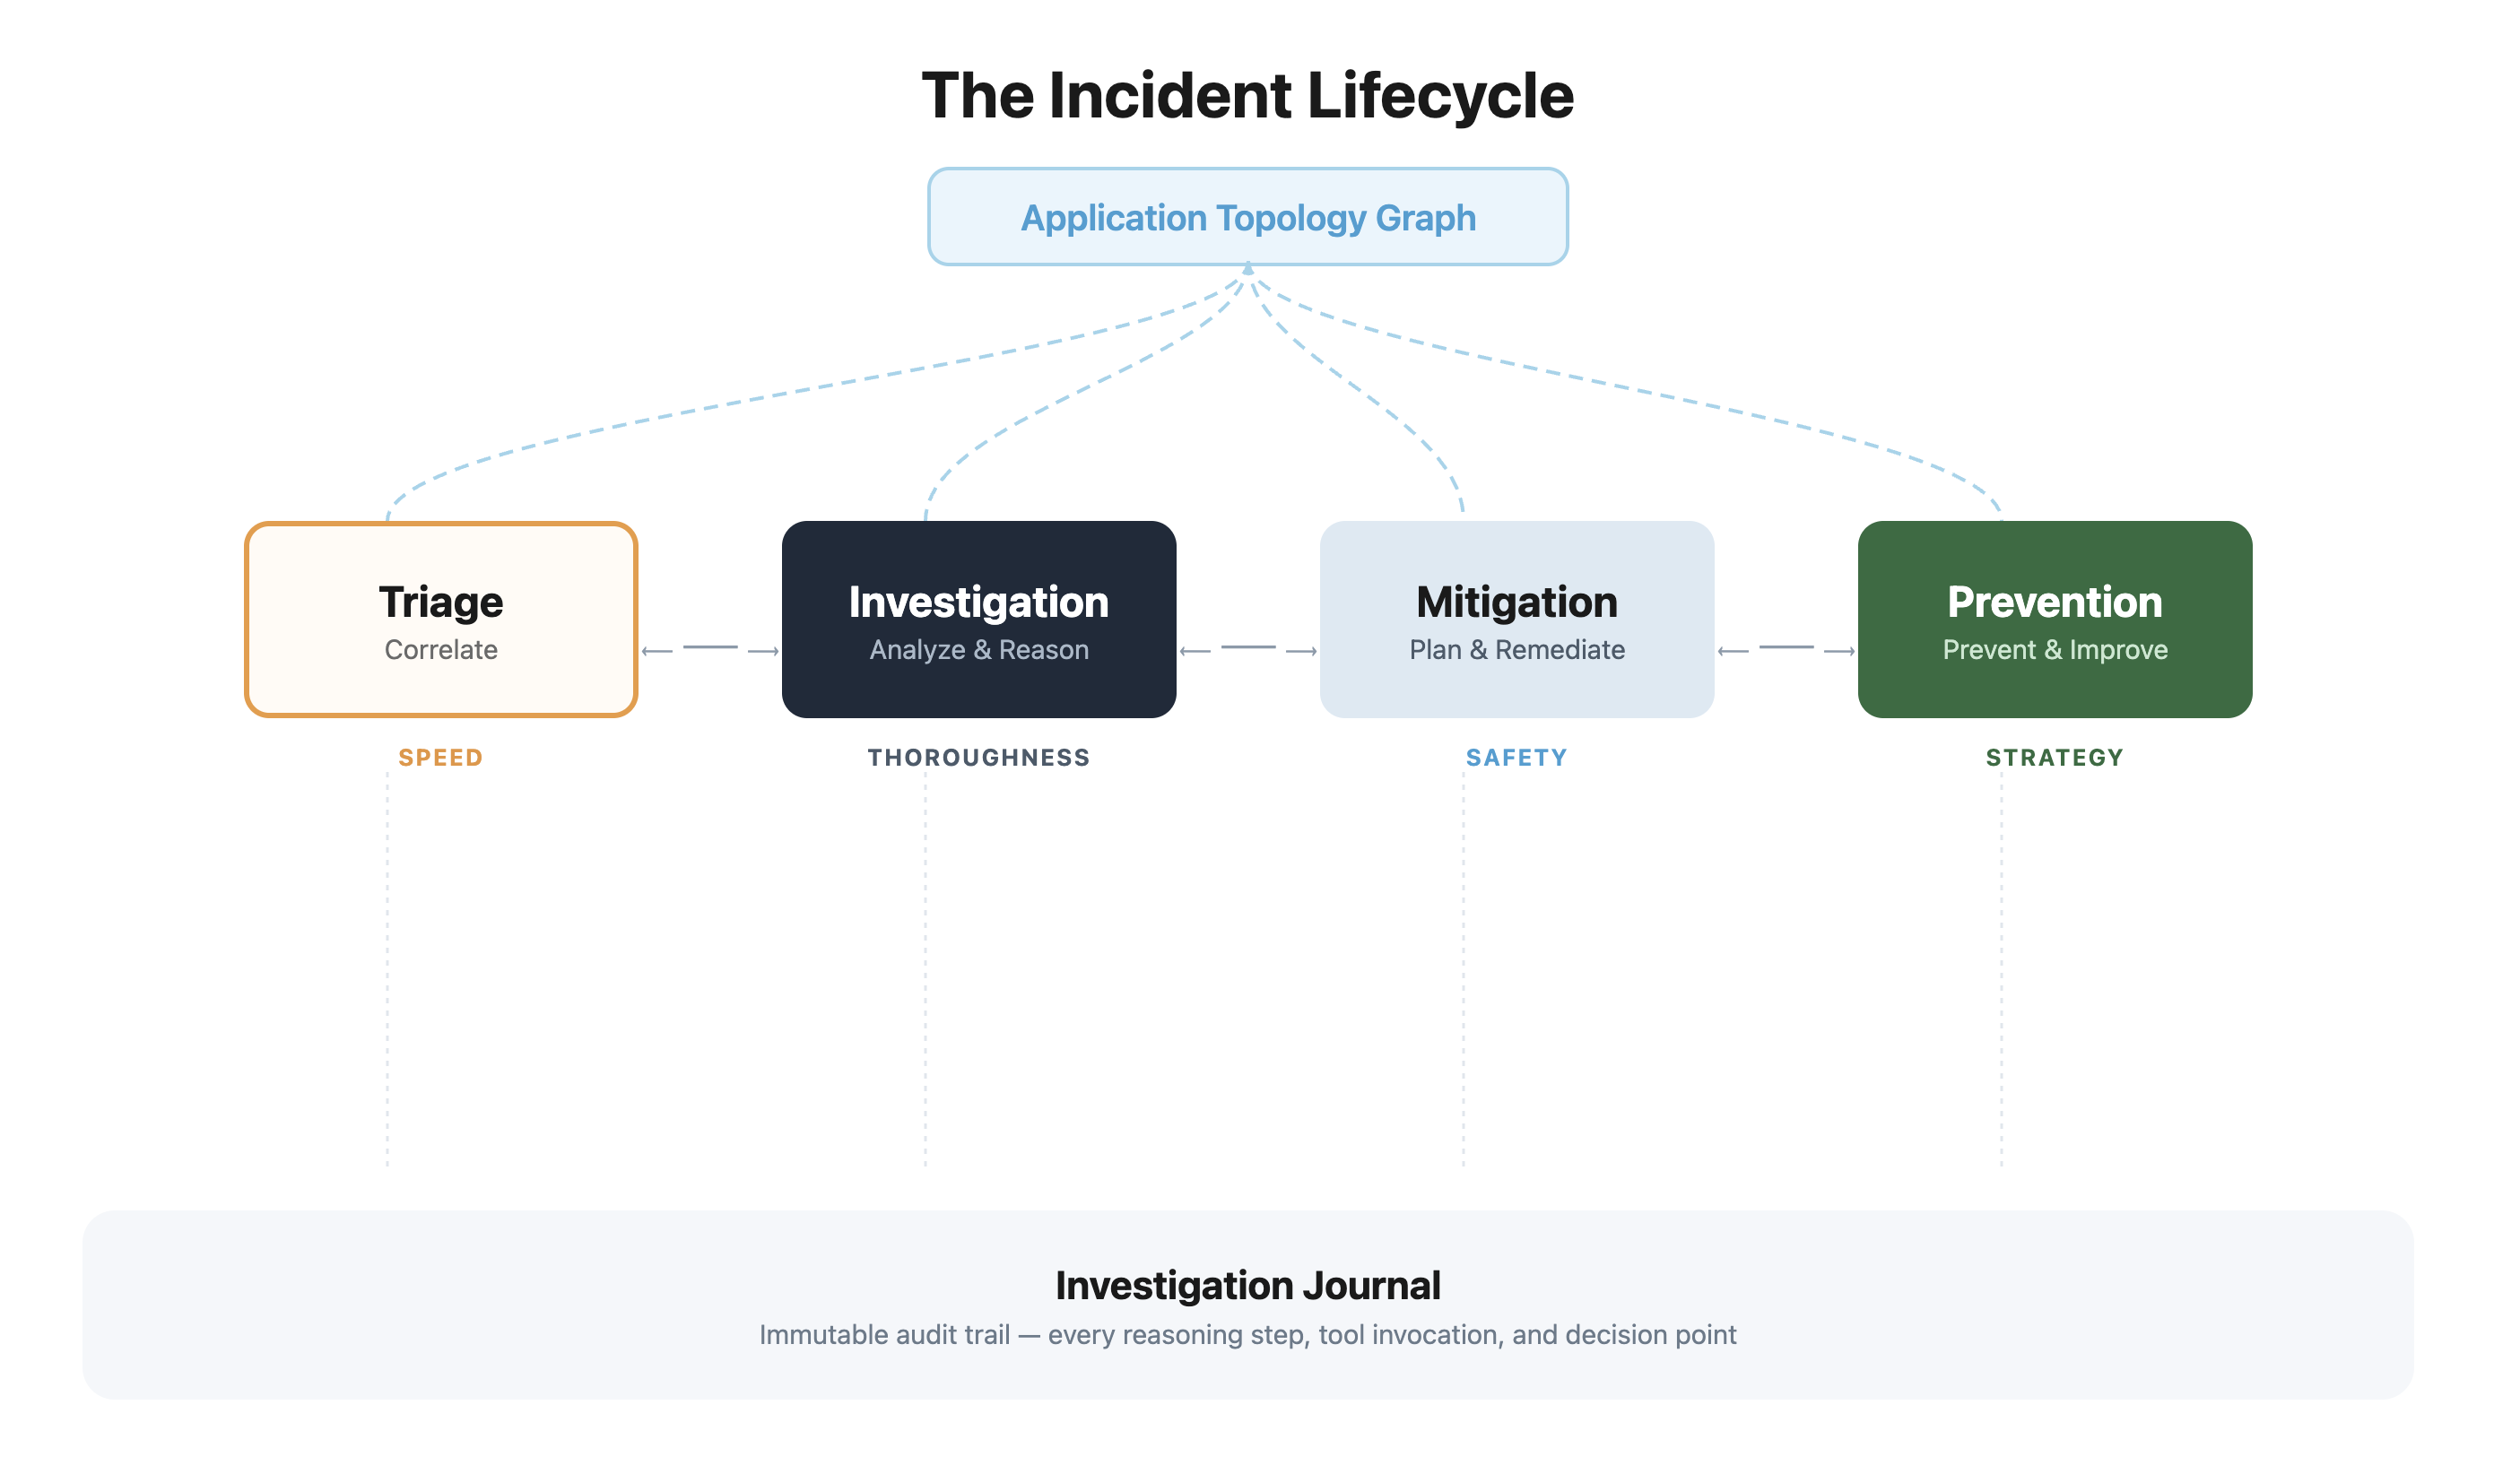
The Incident Lifecycle

AWS DevOps Agent organizes incident response into multiple capabilities that mirror how the best SRE teams operate — each purpose-built for a different operational priority, all sharing a common architectural foundation.

ncident lifecycle with stages: Triage, Investigation, Mitigation, and Learning, connected by an Application Topology Graph and Investigation Journal
The topology graph provides the architectural foundation. The Topology Graph feeds context across the lifecycle and the Investigation Journal runs as a continuous audit trail beneath it. Each capability above it is purpose-built for a different operational priority.

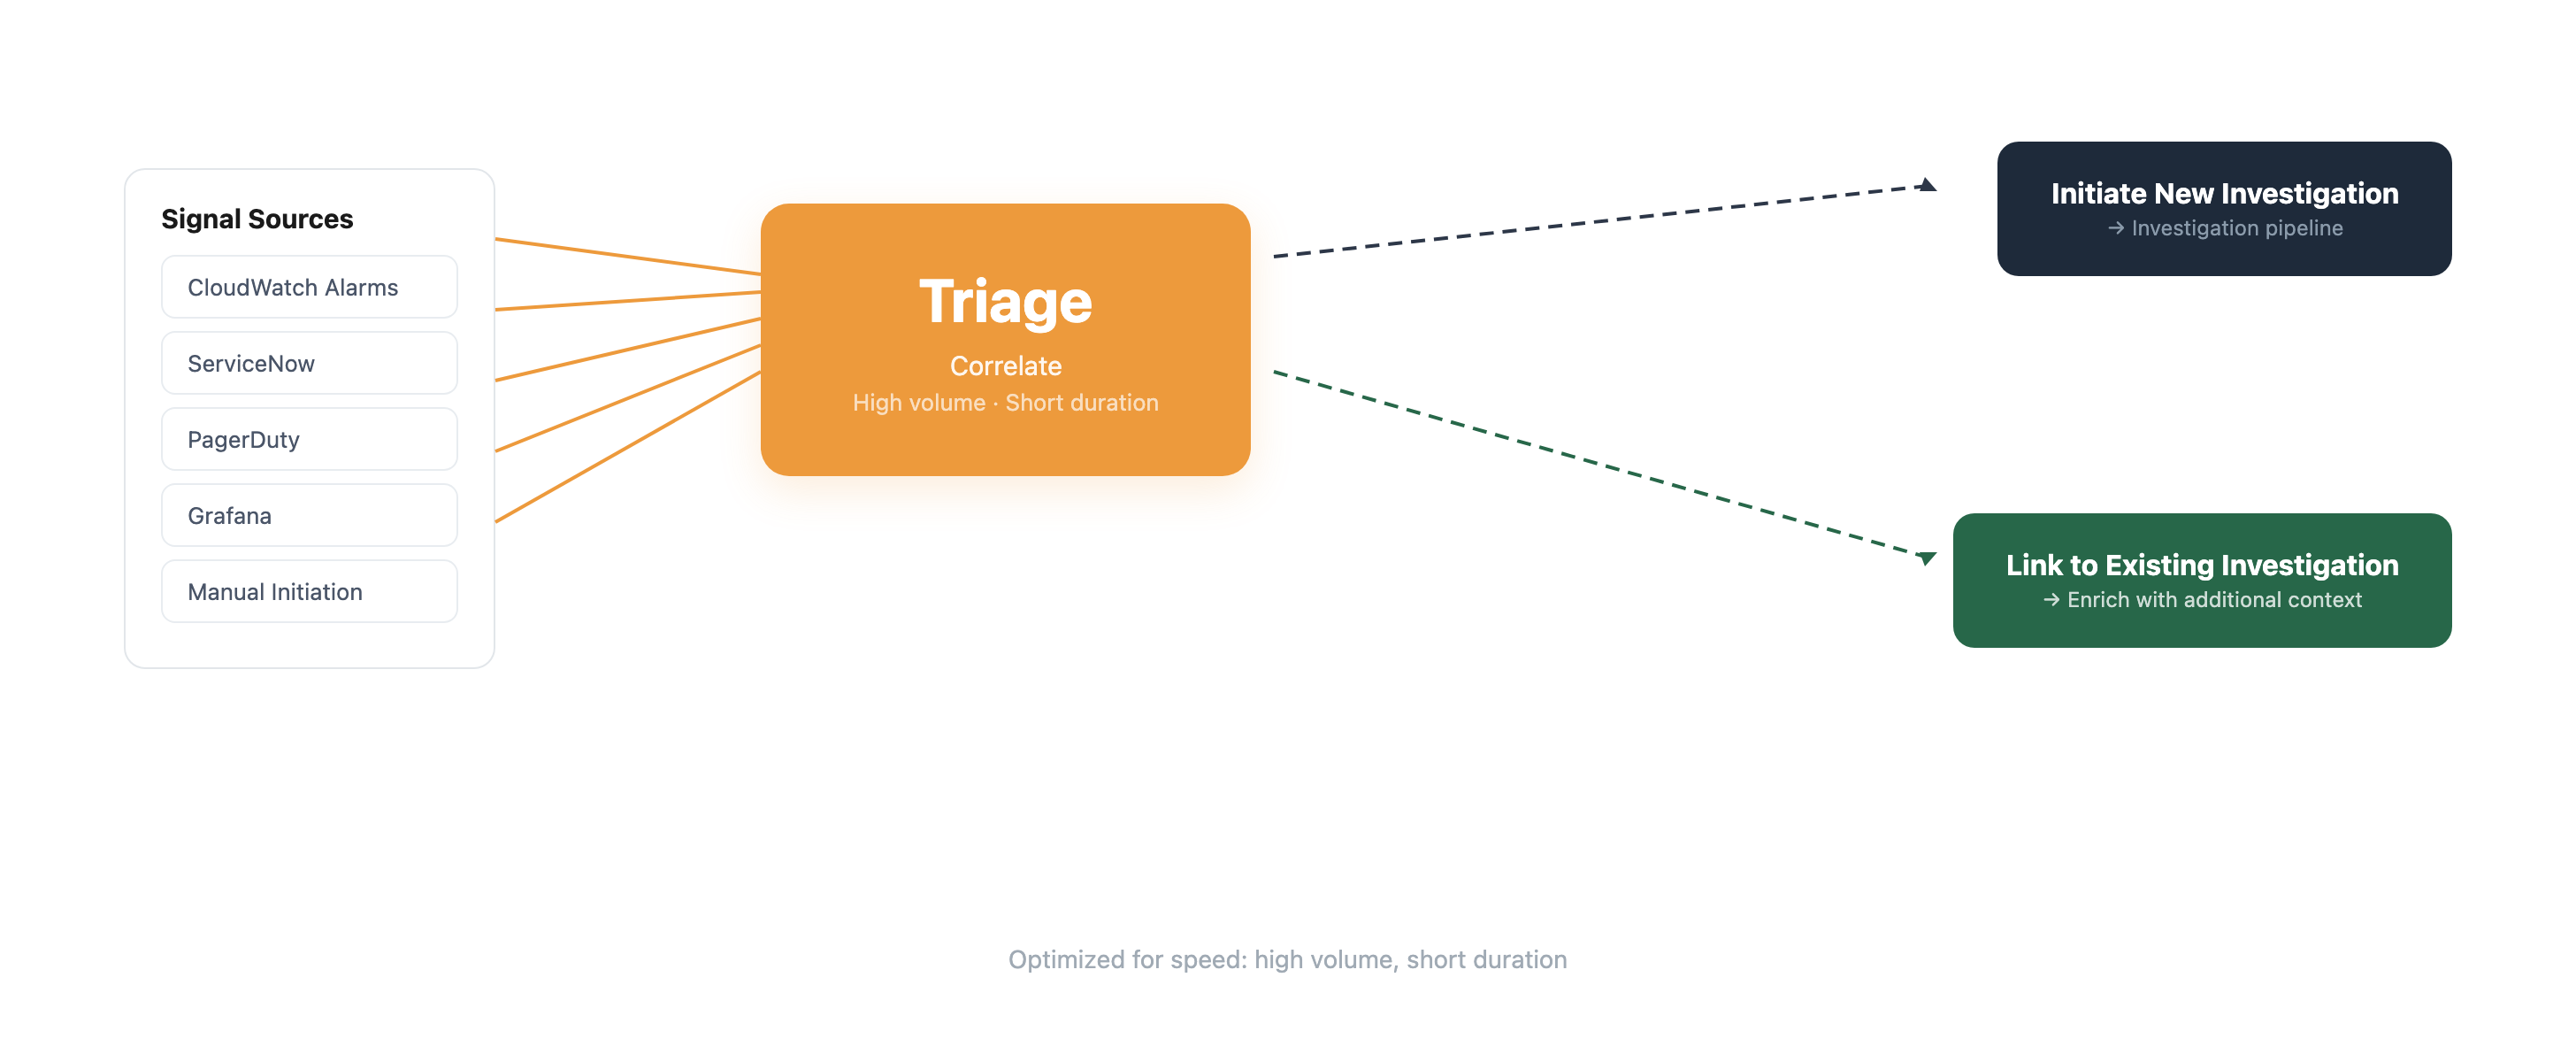
    • Triage — Correlates incoming signals with related alerts and enriches investigations with correlation context. Optimized for speed.
    • Investigation — Deep multi-phase root cause analysis with parallel hypothesis generation and counter-evidence validation. The core reasoning engine.
    • Mitigation — Generates immediate remediation actions based on the root cause identified by Investigation.
    • Prevention — Analyzes patterns across historical incidents to prevent future occurrences.

All capabilities share a critical dependency: the application topology graph. Before we follow an incident through the lifecycle, let’s look at how that foundation is built.

Topology: The foundation everything depends on

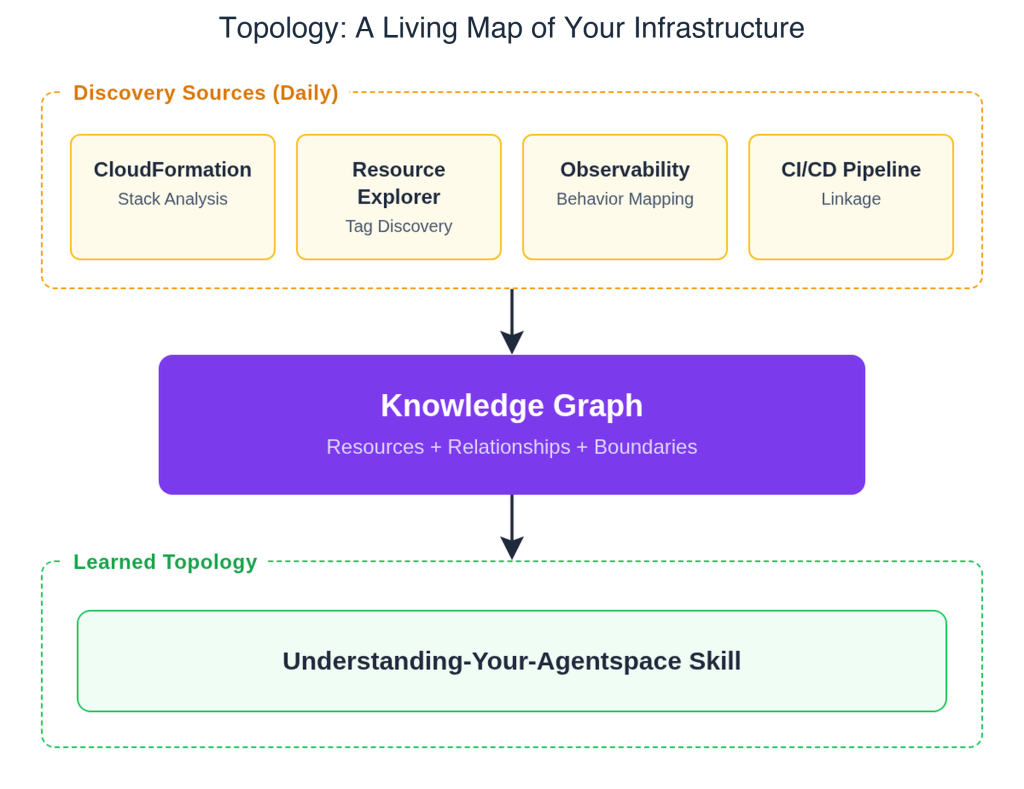
Before the agent can investigate an incident, it needs to understand your architecture — not just a static inventory of resources, but a living map of how they relate, how they communicate at runtime, and how they connect back to the code that deploys them.

Topology engine showing four discovery sources feeding a Knowledge Graph, which powers a learned topology created by the understanding-your-agentspace skill
The topology engine builds this understanding through complementary discovery approaches: AWS CloudFormation stack analysis (including AWS CDK since it synthesizes to AWS CloudFormation), tag-based discovery through AWS Resource Explorer, behavioral mapping through CloudWatch Application Signals and third-party platforms like Dynatrace, Datadog etc. that reveals runtime communication patterns, and CI/CD pipeline integration like GitHub Actions, GitLab CI/CD that links resources back to deployment processes and specific code changes.

The result is a learned topology — built and continuously refined by the understanding-your-agentspace skill — that captures static infrastructure relationships, runtime communication patterns, and deployment lineage. When Investigation needs to trace a failure through dependencies, it follows the graph’s edges. When Mitigation needs to assess the impact radius of a proposed fix, it checks the graph’s relationship map. Without this foundation, the agent would be searching blindly through telemetry. With it, the agent reasons about your system with architectural context – following dependencies, checking blast radius, and correlating with recent changes.

All of this operates within an Agent Space — a logical container scoped to a team, service, or application. Each Agent Space maintains its own topology graph, investigation history, and integrations in full isolation from other spaces.

With the architectural foundation in place, let’s follow an incident through the lifecycle.

Triage: Fast classification and correlation

When an incident arrives — whether from CloudWatch Alarms, third-party tools like ServiceNow, PagerDuty, or Grafana, or through manual initiation — Triage activates first.

Triage receiving signals from different sources and correlating them to enrich investigations with context.Triage is optimized for speed — high volume, short duration. It correlates incoming signals with related alerts and enriches investigations with correlation context.
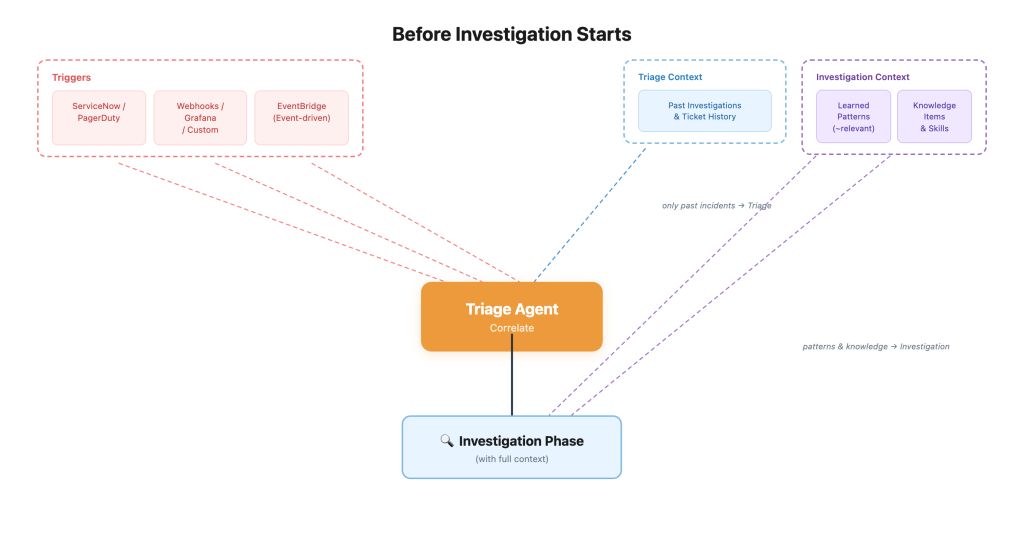
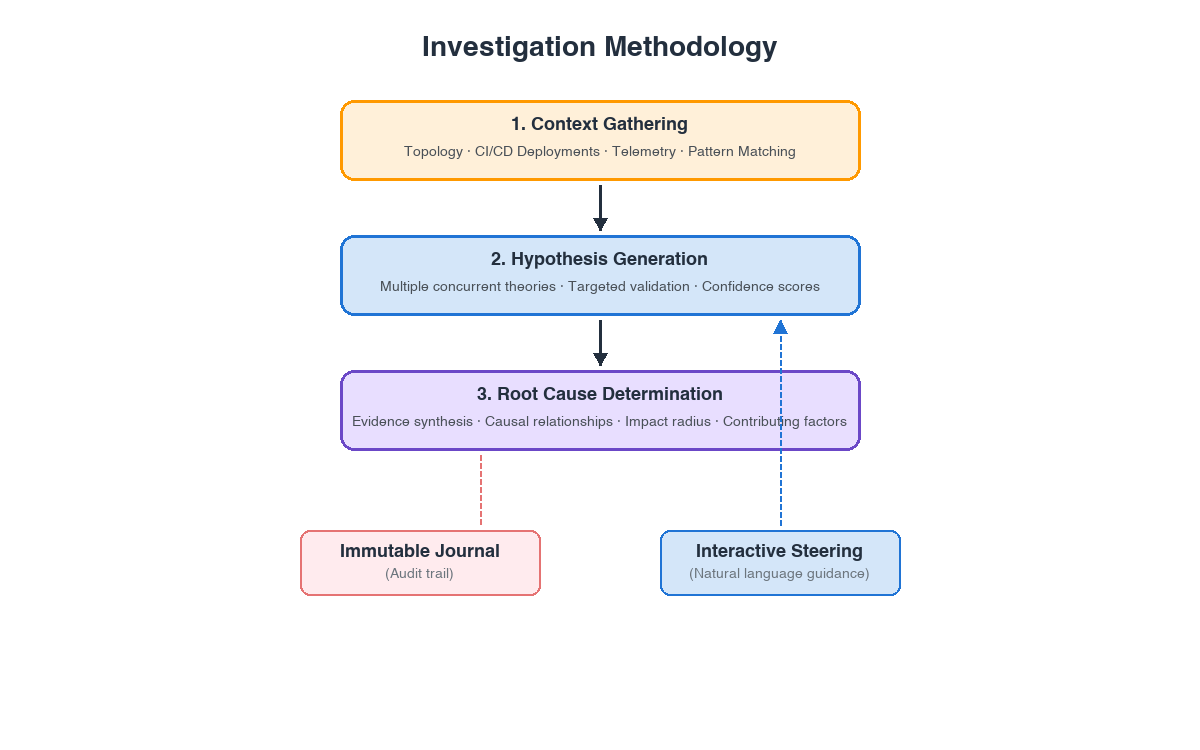
A key part of Triage is correlation: the agent automatically correlates related alarms to identify when they originate from the same event. This accelerates incident response by immediately understanding which alarms are related and which require separate investigation — reducing noise and enabling teams to focus on the most critical issues first. In a complex distributed system, a single root cause can generate alerts across different services and monitoring tools; without correlation, each alert would spawn its own investigation, fragmenting the response team’s attention. With it, the agent funnels related evidence into a single, comprehensive investigation.

Correlation isn’t a one-way door. If the agent links alerts that an operator believes are unrelated, the operator can unlink them and spawn a separate investigation. The agent makes the initial correlation decision at machine speed; the human retains full control to override it.

Once Triage has correlated the incoming signals and enriched the investigation with context, the Investigation capability begins its deep analysis.

Investigation: The Reasoning Engine

Investigation is the centerpiece — where AWS DevOps Agent’s architecture diverges from conventional AI-assisted troubleshooting. It follows a structured methodology that mirrors how experienced DevOps engineers work: acquire context about what’s affected and what changed, collect evidence across every connected data source, generate multiple competing hypotheses simultaneously, subject each to both supporting and counter-evidence validation, and converge on root cause only when the evidence demands it. Operators can steer the investigation at any point through natural language, with the journal recording how those inputs influenced the agent’s reasoning.

Context Acquisition and Data Collection

Every investigation starts with two questions: what’s affected and what changed recently?

The agent parses the incoming signal to understand scope — which resources show symptoms, what time window matters, and what the operator already knows. It then walks the topology graph outward from those resources, mapping the blast radius: direct dependencies, upstream producers, downstream consumers. It pulls recent deployment activity from connected CI/CD pipelines and checks whether the current pattern resembles anything it has investigated before.

With that situational map in hand, the agent casts a wide evidence net. It pulls time-series metrics alongside a healthy baseline so it can spot deviations, not just absolute values. It queries log streams across connected observability platforms — CloudWatch, Splunk, Datadog — filtered to the relevant resources and error signatures. It collects distributed traces showing how requests flowed through affected paths. It also captures configuration state and assembles a chronological timeline of deployments, config changes, scaling events, and alarm triggers.

Triage Agent correlating triggers with past incident history to enrich the Investigation phase, which draws on additional historical context.

Hypothesis Generation

With evidence collected, the agent generates multiple competing root-cause theories simultaneously — each one a different lens on the same data.

Some hypotheses come from pattern matching: the symptoms resemble a known failure signature from previous investigations. Others emerge from anomaly detection: a metric that was stable for weeks just deviated sharply from its baseline. The agent also checks temporal correlation with recent deployments, evaluates whether upstream or downstream services are showing their own problems, and looks at resource constraints — connection pools, CPU headroom, quota limits — that could explain degradation under load.

The investigation methodology: Context Gathering, Hypothesis Generation, and Root Cause Determination with Journal and  Interactive Steering.The agent pursues multiple hypotheses simultaneously, validating each with both supporting evidence and counter-evidence before surfacing them to operators. As the agent builds the causal chain, it classifies validated hypotheses as either a ’cause’ or ‘root cause’ based on their connection to the incident, and labels unconnected findings as hypothesis.
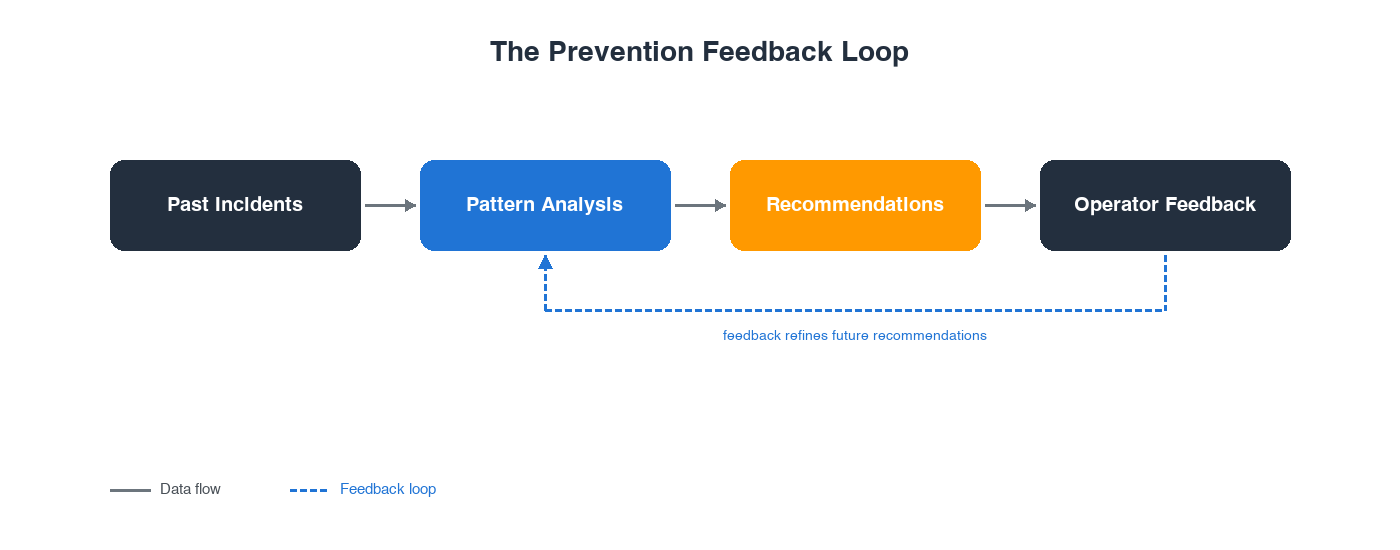
Evidence Gathering and Root Cause Determination

The agent validates multiple hypotheses simultaneously, testing each against both supporting and counter-evidence before surfacing them to operators.

Here’s what that looks like in practice. An e-commerce platform’s checkout service — the critical path between a customer clicking “Place Order” and payment processing — starts showing latency spikes during peak traffic. Orders are timing out, and the on-call team is getting paged.

The agent generates three hypotheses: a config change was pushed 20 minutes before onset, the payment gateway is returning slow responses, and the database connection pool is nearing capacity. All three are plausible — an engineer under pressure might pick whichever one they check first and run with it. The agent checks all three simultaneously. It examines the config change and finds it only affected logging verbosity — it couldn’t have impacted request latency. Theory eliminated. It confirms the payment gateway is indeed slow, but digs deeper and discovers that slowness started after the checkout latency began — the gateway is a symptom, not the cause. Theory eliminated. The connection pool, at 94% capacity, correlates with the exact onset time — and nothing contradicts it. That’s the root cause.

The agent then synthesizes evidence across remaining hypotheses — distinguishing correlation from causation, identifying primary and contributing causes, and flagging ambiguity when evidence isn’t conclusive.

With root cause established, the investigation’s final output is a structured mitigation plan — and this is where the agent’s safety-first design becomes critical.

Mitigation: Safe by default

The mitigation plan follows a deliberate structure: remediation strategy, step-by-step procedures, validation checks to verify system state before applying changes, success criteria to assess whether the fix worked, and rollback procedures to reverse it if something goes wrong.

AWS DevOps Agent generates mitigation plans but does not execute remediation actions on the operator’s behalf — the agent’s write capabilities are restricted to ticket and support case creation. The plans themselves can recommend write actions including specific commands, configuration changes, or code modifications, but execution remains with the operator. Every plan includes rollback procedures to reverse the mitigation if it introduces new problems. The agent uses topology awareness to assess the blast radius before recommending any change — the same graph that helped trace the root cause now helps understand the impact of the proposed fix.

This is a deliberate design choice. In production incident response, the most dangerous moment isn’t when you’re investigating — it’s when you’re applying a fix under pressure. By separating the recommendation from the execution, the agent helps ensure that a human reviews the plan, validates the rollback procedure, and makes the conscious decision to proceed.

Prevention: From reactive to proactive

The most valuable pattern the agent finds isn’t in any single incident — it’s across incidents. The Prevention capability clusters past incidents by shared root causes, even when their surface symptoms looked completely different. A latency spike in your API, a timeout in your batch processor, and an error rate in your notification service might all trace back to the same database scaling issue — but without pattern analysis, they appear as three unrelated incidents.

Prevention feedback loop flowing from Past Incidents through Pattern Analysis and Recommendations to Operator Feedback, which loops back to refine future recommendations
These patterns produce targeted recommendations across observability enhancements like monitoring gaps, alert tuning, and tracing coverage; testing and validation improvements like deployment validation and chaos engineering practices; code resilience patterns like retry logic, circuit breakers, and error handling; infrastructure optimization like capacity planning, autoscaling, and right-sizing; and governance guardrails like pipeline bake time suggestions, test validation gates, and pipeline integration tests.

Recommendations aren’t static. Operators accept them into their backlog or reject them with natural language feedback that refines future suggestions. Recommendations persist until operators explicitly act on them, keeping teams in control of their backlog.

Investigation can help reduce mean time to resolution. Prevention can help reduce incident count. Over time, fewer incidents compound into significant engineering hours saved — and the agent’s recommendations become more targeted with every cycle. The more it investigates, the more it prevents. The more it prevents, the fewer incidents your team faces.

Conclusion

AWS DevOps Agent connects these capabilities into an operational flywheel. The topology graph gives every stage architectural awareness — Investigation follows it to trace failures, and Mitigation checks it to assess blast radius. Investigation findings flow into Prevention, which clusters them to find patterns that individual incidents can’t reveal. Prevention recommendations improve the environment, which changes what the next investigation encounters — each cycle can make the system stronger and the next incident faster to resolve.

If you’ve been on call, you know the pressure — it’s late in the night, you’re switching between dashboards, notifications are flooding in, and you’re weighing whether the fix you’re about to apply could make things worse. AWS DevOps Agent is built to help in that moment — competing theories have already been tested against counter-evidence, the reasoning is documented in an immutable journal, and the mitigation plan includes rollback procedures.

The topology graph, investigation history, and prevention recommendations persist across team changes. Operational context that once lived only in an engineer’s head now lives in the system — available to whoever is on call next.

We’d love to hear how you approach incident investigation — what’s worked, what hasn’t, and what you’d want an AI agent to handle. Share your thoughts in the comments below.

Create your first Agent Space within AWS DevOps Agent in the AWS Management Console and start your first investigation.

Harish Mandhadi

Harish Mandhadi is a Sr Technical Account Manager at AWS, where he provides strategic technical guidance to retail industry customers with a focus on resilience and agentic AI domains. Outside of work, Harish enjoys spending time outdoors doing activities like motorcycle riding, crossfit and spending time with his family.

Automate root cause analysis across Datadog and Elasticsearch with AWS DevOps Agent

Post Syndicated from Bhuvan Jain original https://aws.amazon.com/blogs/devops/automate-root-cause-analysis-across-datadog-and-elasticsearch-with-aws-devops-agent/

Modern distributed systems route business transactions through dozens of microservices, message queues, and event streams. When a message fails to process or processing exceeds SLA thresholds, troubleshooting requires correlating logs from tools like Elasticsearch, metrics from Datadog, and infrastructure change events in AWS CloudTrail. Correlating these signals manually across heterogeneous backends, each with different query languages, schemas, and time granularities, can take hours per incident and demands deep institutional knowledge of the system topology.

This post shows how AWS DevOps Agent, combined with a custom Model Context Protocol (MCP) server for Elasticsearch and native Datadog integration, automates end-to-end root cause analysis. When a Datadog alert fires, AWS DevOps Agent automatically initiates an investigation, correlates signals across all observability backends, and delivers root cause findings in minutes, without manual intervention.

In this post, we walk through the architecture, configuration steps, and a real-world scenario demonstrating how AWS DevOps Agent dramatically reduces mean time to identify (MTTI) for distributed system failures. DevOps engineers, site reliability engineers (SREs), and operations leaders managing containerized workloads will learn how to implement alert-triggered automated investigations that eliminate manual correlation and accelerate root cause identification in their own environments.

Challenges in correlating telemetry signals at scale

At scale, correlating telemetry signals across distributed systems is a key challenge. A platform processing billions of communications for regulated industries must track every message through its full lifecycle — ingestion, transformation, policy evaluation, archival, and retrieval — across dozens of production clusters, thousands of worker nodes, and terabytes of daily telemetry spread across multiple observability backends. A single message ID can generate log entries across multiple indices, correlated metrics in monitoring systems, and change events in audit trails. When a message goes missing or processing stalls, the operations team must pinpoint which cluster processed it, which log store holds the evidence, whether a recent deployment preceded the failure, and whether the issue is isolated or systemic — all while context-switching across tools with different query languages and data schemas. Before AWS DevOps Agent, this process routinely took hours per incident, and longer for complex multi-service failures.

The core difficulty is not the volume of data. It is the correlation of signals across heterogeneous systems that use different identifiers, different time granularities, and different data schemas. A message ID in Elasticsearch logs must be correlated to:

  • A trace ID in application performance monitoring (APM) systems
  • A pod name and namespace in Kubernetes event logs
  • A container image tag in Amazon Elastic Container Registry (ECR) push events
  • Metric anomalies (error rate spikes, pod restarts, CPU/memory deviations) in Datadog
  • Deployment events captured in AWS CloudTrail logs

Manual correlation requires engineers to maintain mental models of these relationships while executing queries across multiple systems. It is error-prone, non-repeatable, and heavily dependent on institutional knowledge. When the engineer with the deepest system familiarity is unavailable, resolution times increases.

Prerequisites

Complete the following prerequisites before configuring the integrations:

  1. The AWS Command Line Interface (AWS CLI) version 2. For installation instructions, see installing or updating to the latest version of the AWS CLI.
  2. Helm – the Kubernetes package manager used to deploy the sample application.
  3. Kubectl – the Kubernetes command-line tool used to deploy Filebeat and manage cluster resources.
  4. An EKS cluster with Control plane logs enabled.
  5. AWS DevOps Agent Agentspace. For installation instructions, refer to Creating an Agent Space.
  6. Elasticsearch cluster deployed and accessible (EC2-hosted, Amazon OpenSearch Service, or self-managed). Filebeat configured as a DaemonSet to collect pod logs and forward to Elasticsearch.
  7. Datadog account with API key and application key. To create, see API & Applications key.

Solution Architecture

The solution presented in this post combines three integrated components to deliver automated end-to-end message ID traceability:

  • AWS DevOps Agent as the intelligent investigation orchestrator
  • A custom ELK MCP Server providing structured access to Elasticsearch log data
  • Native Datadog integration for metrics, events, and alert-triggered investigations

Together, these components form an autonomous investigation pipeline that activates when an alert fires, correlates signals across all observability sources, builds a topological understanding of the affected services, and delivers a structured root cause analysis, without manual intervention.

In our implementation, application pods are instrumented to emit custom metrics to Datadog, including per-message-ID processing status, trace ID labels, and endpoint-level error counters. This instrumentation provides AWS DevOps Agent with the ability to correlate a specific message ID from an alert payload to its corresponding trace ID in application performance data, a correlation that previously required manual cross-referencing.

Webhook-Based Alert Triggering

A critical aspect of the architecture is the automated triggering of investigations when alerts fire. Rather than requiring manual investigation initiation, the solution configures Datadog alerting webhooks to invoke AWS DevOps Agent directly.

When a Datadog monitor enters an alert state, it fires a webhook to the AWS DevOps Agent endpoint, including:

  • The message ID associated with the processing failure
  • The trace ID for APM correlation
  • The alert timestamp and alert condition
  • The triggering monitor name and severity

AWS DevOps Agent authenticates the webhook using a bearer token and immediately initiates an investigation in the configured Agent Space. The Datadog webhook payload serves as the investigation’s initial context, seeding the agent with the specific identifiers it needs to perform targeted queries rather than broad searches across the full data volume.

Architecture Diagram

Architecture diagram showing the automated root cause analysis pipeline. A Datadog alert fires a webhook to AWS DevOps Agent, which queries three sources: an ELK MCP Server connected to Elasticsearch for log data, native Datadog integration for metrics, and AWS CloudTrail for deployment events. Results flow back to the Agent Space for correlated root cause analysis.
Figure 1:
Automated root cause analysis pipeline — from Datadog alert to AWS DevOps Agent investigation across Elasticsearch, Datadog, and AWS CloudTrail

Implementation Walkthrough

The following walkthrough describes the end-to-end setup required to replicate the message ID traceability solution in your own environment.

Step 1: Configure EKS Cluster Access for AWS DevOps Agent

AWS DevOps Agent requires an access entry in each EKS cluster it will investigate. This enables the agent to describe Kubernetes objects, retrieve pod logs, and access cluster events.

  1. In the AWS DevOps Agent console, navigate to your Agent Space and select the Capabilities tab.
  2. Under the Cloud section, select the primary source and choose Edit. Note the Role Name shown in the Role Name field, this is the IAM role that requires EKS access.
  3. In the Amazon EKS console, select each cluster and open the Access tab.
  4. Under IAM Access Entries, choose Create to add a new access entry.
  5. Set the IAM Principal ARN to the Agent Space role noted in step 2.
  6. Under Access Policies, select AmazonAIOpsAssistantPolicy with Cluster scope. Choose Add Policy, then Next.
  7. Review and create the access entry.

At scale: For environments with 50+ clusters, use the AWS CLI, Terraform, or a GitOps pipeline to automate access entry creation across all clusters. The following CLI command creates an access entry for a single cluster:

aws eks create-access-entry --cluster-name <CLUSTER_NAME> --principal-arn <AGENTSPACE_ROLE_ARN> --region <REGION>
aws eks associate-access-policy --cluster-name <CLUSTER_NAME> --principal-arn <AGENTSPACE_ROLE_ARN> --policy-arn arn:aws:eks::aws:cluster-access-policy/AmazonAIOpsAssistantPolicy --access-scope type=cluster --region <REGION>

Step 2: Configure Datadog Integration in AWS DevOps Agent

AWS DevOps Agent includes native Datadog integration. Configuration requires your Datadog API credentials and designates the integration as a data source in the Agent Space. In the AWS DevOps Agent console, navigate to Integrations and choose Add Integration and follow the steps.

After configuration, AWS DevOps Agent can query Datadog metrics, monitors, and events during investigations. Custom application metrics (message throughput, error rates, processing status per message ID) are automatically accessible once the integration is active.

Step 3: Deploy and Configure the Custom ELK MCP Server

The Elasticsearch MCP server bridges AWS DevOps Agent to your self-managed Elasticsearch deployment. The MCP server is deployed as a publicly accessible endpoint with TLS authentication, enabling AWS DevOps Agent to call Elasticsearch APIs securely without requiring direct network access to the actual Elasticsearch/Kibana instances.

Note: For basic Elasticsearch integration, the official Elasticsearch MCP server provides a ready-to-use option. For this use case, we built a custom Python MCP server using FastMCP to expose investigation-specific tools — trace ID correlation, time-window log retrieval, and latency analysis — tailored to our message traceability workflow.

The custom server implementation provides the thirteen tools required for log search, index discovery, and aggregation.

Table: ELK MCP Server tools access by AWS DevOps Agent during investigations
MCP Tool Description
search_logs Search by Lucene query string, time range, and log level
get_error_summary Top recurring errors within a time window
get_recent_logs Fetch most recent log entries from an index
get_logs_by_service Filter logs by service or application name
count_logs_by_level Breakdown of log counts by level (ERROR, WARN, INFO, DEBUG)
get_slow_requests Find requests exceeding a latency threshold
get_logs_around_time Fetch logs within ±N minutes of a specific timestamp
search_by_trace_id Find all logs for a specific trace, request, or correlation ID
get_unique_errors Get distinct error messages in a time window
list_indices List all available Elasticsearch indices with doc counts and health
get_index_stats Get size, document count, and health of a specific index
get_logs_by_host Filter logs by the hostname that sent them via Filebeat
get_logs_by_file Filter logs by the source log file path
  1. Launch an Ubuntu instance (t4g.medium or larger) with a security group allowing inbound TCP 443 from AWS DevOps Agent service endpoints.Note: The single-instance deployment described here is intended for demonstration purposes and does not provide high availability. For production workloads requiring managed infrastructure, automatic scaling, and built-in resilience for your MCP servers, consider using Amazon Bedrock AgentCore Runtime.
  2. Install dependencies and obtain a TLS certificate:
    sudo apt update &&sudo apt install -y python3 python3-venv certbot
    python3 -m venv ~/elk-mcp-venv
    source ~/elk-mcp-venv/bin/activate
    pip install mcp elasticsearch uvicorn starlette
    sudo certbot certonly --standalone -d elk-mcp.yourcompany.com
  3. Create the MCP server. The key architectural decisions are: FastMCP for the Streamable HTTP transport, Starlette middleware for API key authentication, and environment variables for configuration:
    import json, os
    from mcp.server.fastmcp import FastMCP
    from elasticsearch import Elasticsearch
    from starlette.middleware.base import BaseHTTPMiddleware
    from starlette.responses import JSONResponse
    
    ES_HOST = os.environ.get("ES_HOST", "http://localhost:9200")
    API_KEY = os.environ.get("MCP_API_KEY", "YOUR_API_KEY")
    es = Elasticsearch(hosts=[ES_HOST])
    mcp = FastMCP("elk-logs", host="elk-mcp.yourcompany.com")
    
    # API key authentication middleware
    class APIKeyMiddleware(BaseHTTPMiddleware):
        async def dispatch(self, request, call_next):
            if request.headers.get("x-api-key") != API_KEY:
                return JSONResponse({"error": "Unauthorized"}, status_code=401)
            return await call_next(request)
    
    # Example: trace ID correlation tool
    @mcp.tool
    def search_by_trace_id(trace_id: str, index: str, size: int = 100) -> str:
        """Find all logs for a specific request or trace ID."""
        result = es.search(index=index, body={
            "query": {"multi_match": {
                "query": trace_id,
                "fields": ["trace_id", "request_id", "correlation_id", "traceId"]
            }},
            "sort": [{"@timestamp": "asc"}],
            "size": size
        })
        return json.dumps([h["_source"] for h in result["hits"]["hits"]], indent=2)
    
    # ... additional tools follow the same pattern
    
    app = mcp.streamable_http_app()
    app.add_middleware(APIKeyMiddleware)
    
    if __name__ == "__main__":
        import uvicorn
        uvicorn.run(app, host="0.0.0.0", port=443,
            ssl_keyfile="/etc/letsencrypt/live/elk-mcp.yourcompany.com/privkey.pem",
            ssl_certfile="/etc/letsencrypt/live/elk-mcp.yourcompany.com/fullchain.pem")
  4. Start the server:
    sudo -E ES_HOST=http://<ELASTICSEARCH_IP>:9200 MCP_API_KEY=<YOUR_API_KEY> nohup ~/elk-mcp-venv/bin/python ~/elk_mcp_server.py > ~/mcp.log 2>&1 &
  5. Register in AWS DevOps Agent:
    1. In the AWS DevOps Agent console, navigate to Integrations -> Add MCP Integration.
    2. Enter the endpoint URL: https://elk-mcp.yourcompany.com:443/mcp
    3. Enter the API key for authentication.
    4. Verify the integration shows all available tools in the integration detail view.
    5. Add the MCP integration to your Agent Space under the Integrations tab.

Note: The MCP server must be publicly accessible over HTTPS. If your Elasticsearch cluster is in a private VPC, deploy the MCP server with network access to the cluster (e.g., in the same VPC or a peered VPC) while exposing only the MCP server endpoint publicly. Use security group rules to restrict access to AWS DevOps Agent’s known egress IP ranges where possible.

Step 4: Deploy the Application and Configure Filebeat on EKS

Filebeat runs as a Kubernetes DaemonSet on each EKS cluster, collecting pod logs and enriching them with Kubernetes metadata before forwarding to Elasticsearch. The following pipeline configuration ensures that message IDs and trace IDs are preserved as indexed fields, enabling efficient targeted queries during investigations.

  1. Clone the Repository and Build the Container Image:
    # Clone the DevOps agent sample repository
    git clone https://github.com/aws-samples/Amazon-prometheus-bedrock-agent-example.git
    
    # Navigate to the smart demo directory
    cd devops-agent/smart-demo-main/
    
    # Authenticate Docker to your ECR registry
    aws ecr get-login-password --region us-west-2 | docker login --username AWS --password-stdin <your-account-id>.dkr.ecr.us-west-2.amazonaws.com
    
    # Build the container image
    docker build -t sample-app .
    
    # Tag the image for ECR
    docker tag sample-app:latest <your-account-id>.dkr.ecr.us-west-2.amazonaws.com/smart-demp:latest
    
    # Push the image to ECR
    docker push <your-account-id>.dkr.ecr.us-west-2.amazonaws.com/smart-demp:latest
  2. Deploy the Application to EKS:
    # Deploy the sample application to EKS using Helm
    helm install sample-app ./helm --set image.repository=<your-account-id>.dkr.ecr.us-west-2.amazonaws.com/smart-demp --set image.tag=latest
  3. Deploy Filebeat as DaemonSet:
    # Navigate to the Filebeat directory
    cd filebeat
    
    # Apply the Filebeat ConfigMap (autodiscovery, JSON parsing, K8s metadata enrichment, Logstash output)
    kubectl apply -f filebeat-configmap.yaml
    
    # Deploy Filebeat as a DaemonSet on every node in the cluster
    kubectl apply -f filebeat-ds.yaml

Step 5: Configure Datadog Webhook for Automatic Investigation Triggering

We will automatically trigger AWS DevOps Agent investigations when Datadog alerts fire. This eliminates the human latency between alert detection and investigation initiation.

Retrieve the AWS DevOps Agent webhook URL and secret:

  1. In the AWS DevOps Agent console, navigate to your Agent Space and open the Capabilities tab.
  2. Under the Webhook section, choose Configure, then Generate webhook.
  3. Save the webhook URL and HMAC secret. These credentials are used to authenticate webhook requests from Datadog.

In Datadog, configure a webhook integration:

  1. Navigate to Integrations -> Webhooks and create a new webhook.
  2. Set the URL to the AWS DevOps Agent webhook endpoint.
  3. Add the Authorization header with the bearer token from step 3.
  4. Configure the payload to include the message ID, trace ID, and alert context:
    {
    "title": "Message Processing Failure - $EVENT_TITLE",
    "description": "$EVENT_MSG",
    "alert_id": "$ALERT_ID",
    "alert_status": "$ALERT_STATUS",
    "timestamp": "$TIMESTAMP",
    "message_id": "$tags.message_id",
    "trace_id": "$tags.trace_id",
    "service": "$tags.service",
    "cluster": "$tags.cluster_name",
    "severity": "$ALERT_PRIORITY"
    }
  5. Associate the webhook with the Datadog monitors that detect message processing failures by adding @webhook-webhook-name to the monitor notification message.

Step 6: Configure Agent Space Skills (Optional but Recommended)

AWS DevOps Agent Skills provide a Retrieval-Augmented Generation (RAG) knowledge base that gives the agent organization-specific context during investigations. Even a brief skills document (2-3 paragraphs) that identifies your application’s purpose, its key components, and its observability backends can reduce AWS DevOps Agent investigation time by helping the agent understand context before executing its first queries.

In our implementation, the skills document described the sample message-processing application, identified Elasticsearch as the logging backend, and identified Datadog as the metrics backend.

Real-World Investigation: Message Processing Failure Diagnosed in 6 Minutes

The following walkthrough and the scenario represent a common class of incident in distributed systems: a silent functional regression introduced through a new container image deployment that causes specific message types to fail processing without immediately obvious symptoms.

The Scenario

The production EKS cluster runs a message-processing application (sample-app) with four HTTP endpoints:

  • /health – Application health check
  • /metrics – Prometheus metrics endpoint
  • /process – Core message processing endpoint
  • /alert – Alert notification endpoint (newly introduced in recent deployment)

A new container image was pushed to Amazon ECR with a new /alert endpoint. However, the endpoint implementation was incomplete when called; it returned an HTTP 404 response and silently dropped the associated message. The Filebeat DaemonSet collected pod logs and sent them into Elasticsearch. Datadog captured application metrics with message ID and trace ID labels. A Datadog monitor detected the elevated error rate and fired.

Phase 1: Alert Fires and Investigation Initiates (T+0:00)

At 14:52:57 UTC, a Datadog monitor detected an elevated rate of failed message processing requests on the /alert endpoint. The monitor fired a webhook to the AWS DevOps Agent endpoint with the alert payload context.

Within 10 seconds, the Agent read its investigation skills (sample-app-incident and triaging-3p-monitoring-alerts) and began planning the investigation approach.

Screenshot of AWS DevOps Agent console showing an investigation automatically initiated via Datadog webhook. The alert payload context includes message ID, trace ID, and alert timestamp. Investigation skills sample-app-incident and triaging-3p-monitoring-alerts are loaded
Figure 2: AWS DevOps Agent investigation initiated automatically via Datadog webhook, showing alert payload context and investigation skills loaded

Phase 2: Cross-Source Signal Correlation (T+0:10 – T+2:30)

AWS DevOps Agent began its investigation by using the message ID from the alert payload as its primary search key. It decided its investigation strategy: extract the trace_id from Elasticsearch using the message_id, get Datadog monitor details, and search for errors around the alert time.

Elasticsearch Log Search
The agent invoked the ELK MCP server to list available indices and identify the relevant log store for the message-processor application. It then executed a targeted search and identified the relevant Elasticsearch index (logs-2026.03.25):

Screenshot of AWS DevOps Agent querying the ELK MCP Server to correlate a message ID to a trace ID across Elasticsearch indices. The agent identifies the relevant log index logs and retrieves matching log entries
Figure 3: AWS DevOps Agent querying the ELK MCP Server to correlate message ID to trace ID across Elasticsearch indices

AWS DevOps Agent surfaced the Message ID to Trace ID correlation without any explicit cross-referencing instruction. It recognized the relationship from the log structure. At T+1:41, the DevOps Agent launched three parallel tasks simultaneously, rather than investigating sequentially.

Screenshot showing the trace ID successfully resolved from the Elasticsearch log structure, triggering three parallel investigation tasks: Datadog metrics correlation, EKS topology analysis, and CloudTrail event correlation.Figure 4: Trace ID successfully resolved from log structure, triggering three parallel investigation tasks
Datadog Metrics Correlation
Using the trace ID extracted from the Elasticsearch logs, the agent queried Datadog for correlated metrics. It retrieved CPU and memory utilization, pod count, restart metrics and enhanced metrics for request latency and errors.

Screenshot of Datadog metrics retrieved by AWS DevOps Agent using the extracted trace ID, showing CPU utilization, memory usage, pod restart counts, and request latency metrics for the affected service.
Figure 5: Datadog metrics correlation showing CPU, memory, pod restarts, and request latency retrieved using the extracted trace ID

AWS EKS Topology & CloudTrail Event Correlation
AWS DevOps Agent queried AWS CloudTrail for deployment and configuration change events in the time window preceding the alert.

Screenshot of AWS CloudTrail event correlation identifying deployment and configuration change events in the time window preceding the alert, including ECR image push and EKS rolling deployment events
Figure 6: AWS CloudTrail event correlation identifying deployment and configuration changes in the alert time window

With the initial timeline established, AWS DevOps Agent examined all endpoints and their response patterns. This revealed that the application was fundamentally healthy, with three of four endpoints returned consistent 200 responses. However, it also revealed the anomaly was isolated to the /alert endpoint, which had never successfully served a request in its observable history.

Screenshot of AWS DevOps Agent endpoint analysis showing three healthy endpoints returning HTTP 200 responses (health, metrics, process) and the alert endpoint returning consistent HTTP 404 failures, isolating the anomaly to the newly deployed alert endpoint.
Figure 7: AWS DevOps Agent endpoint analysis revealing isolated 404 failures on the /alert endpoint while other endpoints remain healthy

Phase 3: Observation Streaming from Parallel Tasks (T+2:30 – T+3:54)

As the three tasks ran simultaneously, observations streamed in chronologically:

T+2:58 – Observation: Anomalous CPU Behavior Signals Pod Disruption

The first sign of trouble came from pod tr8pl. Its CPU usage dropped sharply. Around the same time, two unfamiliar pods (85bx4, 7h4bd) briefly appeared with minimal CPU. Shortly after, three new pods (hclf9, b7bp2, g6gkc) spun up. This pattern of old pods dying, short-lived intermediaries, and fresh containers starting up pointed strongly toward a rolling deployment in progress.

T+3:04 – Observation: ECR Image Push Traced as the Trigger

With the deployment pattern established, the next question was: what initiated it? CloudTrail provided the answer. At 14:57:19 UTC, a user vik**** (via role nht-admin) pushed a new container image to ECR repository sm***demp:latest (ECR image tag). The timeline now made sense:

  1. ECR image push at 14:57:19 UTC
  2. Rolling deployment (pods replaced)
  3. /alert endpoint 404 errors begin
  4. Datadog alert fires

Screenshot showing parallel task observations streaming into AWS DevOps Agent. Anomalous CPU behavior indicates pod disruption from a rolling deployment, and CloudTrail evidence links an ECR image push by user vik at 14:57:19 UTC to the deployment that introduced the failing endpoint.
Figure 8: Parallel task observations streaming into AWS DevOps Agent – anomalous CPU behavior indicating pod disruption and CloudTrail evidence linking the ECR image push to the rolling deployment

Phase 4: Findings Documented – Causal Chain Established (T+3:55 – T+5:08)

At T+3:55, the Agent documented its first formal Finding (elevated from Observation):

Screenshot of AWS DevOps Agent documenting its formal finding, establishing the causal chain: ECR image push triggered rolling deployment, new container image contained incomplete alert endpoint implementation, endpoint returns 404 and drops messages.
Figure 9: AWS DevOps Agent formal finding documenting the causal chain from ECR image push to alert endpoint failure

Phase 5: Root Cause Confirmation and Infrastructure Validation (T+5:10 – T+5:30)

AWS DevOps Agent validated infrastructure health. The complete absence of infrastructure issues, combined with the timeline evidence from CloudTrail and the historical 404 pattern on the /alert endpoint, allowed AWS DevOps Agent to deliver a high-confidence root cause identification.

At 14:58:12 UTC, exactly 5 minutes and 14 seconds (under 6 minutes) after the investigation began, AWS DevOps Agent delivered its root cause analysis:

Screenshot of the final root cause analysis delivered by AWS DevOps Agent at 14:58:12 UTC, 5 minutes and 14 seconds after investigation began. Root cause identified as an incomplete alert endpoint in the newly deployed container image that returns HTTP 404 and silently drops associated messages.
Figure 10: Final root cause analysis delivered by AWS DevOps Agent, identifying the incomplete alert endpoint in the newly deployed container image

Clean-up

Step 1: Delete the AWS DevOps Agent AgentSpace

  1. In the AWS DevOps Agent console, navigate to Agent Spaces.
  2. Select the Agent Space you created for this walkthrough.
  3. Remove all integrations (Datadog, ELK MCP Server) from the Agent Space by navigating to the Capabilities tab and choosing Remove for each.
  4. Choose Delete Agent Space from Actions dropdown and confirm the deletion.

Step 2: Terminate the Microservices and Delete the EKS Cluster

First, remove the application workloads and Filebeat DaemonSet deployed on the cluster:

# Uninstall the sample application Helm release
helm uninstall sample-app

# Delete the Filebeat DaemonSet and ConfigMap
kubectl delete -f filebeat/filebeat-ds.yaml
kubectl delete -f filebeat/filebeat-configmap.yaml

Once the workloads are removed, delete the EKS cluster.

Step 3: Terminate EC2 Instances

Terminate the EC2 instances hosting both the MCP server and the Elasticsearch cluster. You can do this from the AWS Management Console or the AWS CLI:

# Terminate the MCP server EC2 instance
aws ec2 terminate-instances --instance-ids <MCP_SERVER_INSTANCE_ID> --region <REGION>

# Terminate the Elasticsearch EC2 instances
aws ec2 terminate-instances --instance-ids <ELASTICSEARCH_INSTANCE_ID> --region <REGION>

Conclusion

Distributed systems have created a correlation problem that scales faster than the human capacity to solve it. As microservices architectures grow to span dozens of clusters, hundreds of services, and terabytes of daily telemetry, the manual investigation practices that worked at smaller scale become the primary obstacle in maintaining operational quality.

AWS DevOps Agent addresses this challenge at its root by automating the multi-source correlation that previously required experienced engineers working across multiple systems. The combination of native Datadog integration, custom ELK MCP server connectivity, and AWS CloudTrail access enables AWS DevOps Agent to build the complete picture of an incident: from the first metric anomaly, through the log evidence, to the deployment event that caused it. The scenario described in this post demonstrates that a message processing incident that previously consumed hours can be diagnosed to root cause in under six minutes automatically, without manual intervention, and with the full investigation documented for audit and learning purposes.

About the Authors

Bhuvan Jain

Bhuvan Jain

Bhuvan is a Senior Technical Account Manager at Amazon Web Services, supporting independent software vendor (ISV) customers. He is passionate about helping customers build Well-Architected solutions on AWS, with a focus on enterprise-scale networking. As a subject matter expert, Bhuvan offers guidance on designing network architectures that are highly available, resilient, and cost-effective. He holds a Master’s degree in Electrical and Computer Engineering from the University of Illinois at Chicago (UIC). In his free time, he enjoys playing basketball and volleyball, as well as watching movies and TV series.

Vikram Venkataraman

Vikram Venkataraman

Vikram Venkataraman is a Principal Specialist Solutions Architect at Amazon Web Services. He helps customers modernize, scale, and adopt best practices for containerized workloads on Amazon EKS. With the emergence of AI-powered automation, Vikram has been actively working with customers to leverage AWS AI/ML services to solve complex operational challenges, streamline monitoring workflows, and enhance incident response through intelligent automation. He designed and built the POC architecture described in this post and is a co-author of the EKS knowledge graphs blog.

Building Self-Extending CLI Tools with Strands Agent

Post Syndicated from Ragib Ahsan original https://aws.amazon.com/blogs/devops/building-self-extending-cli-tools-with-aws-strands/

I. Introduction

Engineering teams build internal command-line interface (CLI) tools because repetitive operational tasks such as generating reports, auditing infrastructure, and checking service health are faster and more reliable when automated behind a consistent interface. A well-built CLI replaces ad-hoc scripts with structured commands, standardized error handling, and composable workflows that any team member can run. However, building these tools follows a predictable development lifecycle. The developer sets up a package, writes commands, handles errors, and ships it, then spends the next six months as its sole maintainer. Meanwhile, requests for new commands, custom report formats, and one-off integrations pile up as other teams across the organization discover the tool is useful for their workflows too. Frameworks like Click and Typer reduce the friction, but every new command still needs to be written, tested, and deployed manually.

Tools that generate their own capabilities on demand offer a different approach. Instead of writing each command manually, users can describe what is needed in natural language, and the tool writes the code, loads it, and makes it available at runtime without requiring a restart or redeployment. This is called meta-tooling, a repeatable pattern for giving applications the ability to create their own tools dynamically. For teams that maintain growing collections of internal utilities, this eliminates the bottleneck of having a single developer write every new feature.

In this post, we will walk through one implementation of this pattern, a CLI generator called CLI Creator. CLI Creator combines three technologies into a mechanism that organizations can adapt for their own use cases:

  • Amazon Bedrock, a fully managed service for building generative AI applications with foundation models, with Anthropic’s Claude Opus 4.6 for AI-powered code generation.
  • Strands Agents SDK, an open-source Python framework for building AI agents with tool use, for dynamic tool creation, loading, and execution at runtime.
  • Model Context Protocol (MCP), an open standard for connecting AI applications to external data sources and tools, for automatically discovering API servers that give generated tools additional knowledge.

The result is a development workflow where new CLI capabilities go from request to working command in minutes instead of days, without manual coding. By the end of this post, a single natural language prompt will have produced a complete, installable CLI. That CLI can extend itself with new tools, refine them iteratively, and discover relevant MCP servers through an interactive selection workflow.

II. Solution Overview

The Challenge

As an example, consider a platform engineering team that produces weekly operations reports for leadership. Every Monday morning, stakeholders expect a summary of their AWS footprint, including which Amazon DynamoDB tables are running hot, which Amazon Simple Storage Service (Amazon S3) buckets are growing fastest, and who made significant infrastructure changes last week. The AWS CLI can list tables and buckets, but it cannot produce these reports.

Each report is a multi-step workflow that involves calling several APIs, joining the data, computing derived metrics like estimated monthly cost or growth rate, and formatting the output for a specific audience. The team ends up writing Python scripts for each report, and every new report request means another script by a developer.These are each their own small project, often requiring a hundred lines of Python to pull multiple APIs, compute derived metrics, and format output before you even think about error handling. Requirements shift weekly, so each change means modifying source code, testing, and redeploying. The tooling never converges; the team ends up with a folder of disconnected scripts, each with its own argument parsing, error handling, and output formatting. Any team that builds small, purpose-built utilities faces the same friction, and operations reporting is the example we use to illustrate the meta-tooling pattern.

The Solution

Prerequisites

To follow along with this post, you will need:

  • Python 3.12 or later
  • An AWS account with Amazon Bedrock access enabled for Anthropic Claude models in us-west-2
  • AWS credentials configured locally (via `aws configure` or environment variables)
  • Git installed (for tool version tracking)

The source code is available on GitHub. Installation instructions are in the repository README.

Walkthrough

Instead of writing report scripts manually, organizations describe what they need in natural language.Terminal screenshot of a CLI Creator tool generating an AWS operations reporting CLI called "aws-ops-reporter." The tool analyzes requirements, detects API keywords (DynamoDB, S3, CloudTrail), and displays 18 available MCP servers. The user selects servers 1, 9, and 18 (AWS DynamoDB, AWS S3, AWS CloudTrail). A planned CLI structure shows four commands: dynamo-capacity, unused-s3, audit-cloudtrail, and cost-summary. A confirmation prompt reads "Proceed with generation? [Y/n].

The system then does the following:

  1. Claude Opus 4.6 on Amazon Bedrock analyzes the description and extracts a structured list of commands, arguments, and options.
  2. MCP servers are discovered automatically, wherein the system detects keywords like “DynamoDB”, “S3”, and “CloudTrail” in the description, searches the MCP registry for relevant API servers, and presents an interactive selection prompt for choosing which servers to include.
  3. Once the user confirms, the system generates complete Python code for each command. These are not stubs or placeholders that users may typically see within generated code, but working implementations with validated AWS SDK for Python (Boto3) calls, error handling, and type hints.
  4. Finally, the output is packaged as an installable Python project with a pyproject.toml file and entry points configured.

Most importantly, the generated CLI includes a tool command group that enables self-extension at runtime. After installation, users can ask the CLI to create entirely new reporting tools and iteratively refine them without touching source code. This is the repeatable part of the pattern because any generated tool inherits the ability to extend itself. This mechanism is built into every generated CLI, so each one is immediately capable of growing beyond its original scope.

III. Technical Implementation

Strands Agents SDK Integration

The Strands Agents SDK is the backbone of the meta-tooling pattern. It provides three features that make self-extending tools possible, and these features are not specific to CLI generation. Any Python application can use them to dynamically create and manage capabilities at runtime.

The @tool Decorator

When a user asks a generated CLI to create a new tool, Claude Opus 4.6 on Amazon Bedrock produces Python code that uses the Strands @tool decorator. This decorator registers the function with Strands’ tool system, making it immediately discoverable and executable:

from strands import tool

@tool 
def list_s3_buckets_with_costs() -> List[Dict[str, Any]]:

The @tool decorator registers the function’s signature, type hints, and docstring as a tool specification that the Strands Agent can reason about and invoke.

Runtime Tool Loading

The Strands Agents SDK includes a tool loading system that can discover and import @tool-decorated functions from Python files at runtime. Tools do not need to be registered at application startup. They can be created, saved to a directory, and made available to the agent dynamically.In our implementation, generated tools are saved as standalone Python files in a directory called `tools/`. Each time a CLI command runs, the application scans this directory, loads any @tool-decorated functions it finds, and adds them to the agent’s tool collection without requiring a restart.The self-extending pattern works because of this scan-on-invocation approach. A user can create a tool, execute it, decide it needs changes, update it, and execute again without any rebuild or reinstall step since each CLI invocation discovers and loads whatever tools exist on disk.

Agent Orchestration with BedrockModel

The Strands Agent class ties everything together. It connects to Amazon Bedrock via BedrockModel and manages a collection of tools:

from strands import Agent
from strands.models import BedrockModel

agent = Agent(
    model=BedrockModel(
        model_id=""
    ),
    tools=[shell_tool, editor_tool] + loaded_tools,
    system_prompt="You are a tool creation assistant..."
)

When the agent receives a tool creation request, it calls Amazon Bedrock to generate the implementation and saves it as a Python file in the tools/ directory. The next CLI command automatically discovers and loads the new tool.

Amazon Bedrock Integration

CLI Creator connects to Anthropic’s Claude through Amazon Bedrock’s cross-region inference profile. Amazon Bedrock serves two distinct roles in the system.

Role 1: CLI Requirements Analysis with Structured Output

When you run cli-creator create, the first step is analyzing the natural language description and extracting a structured specification. Instead of parsing raw text from the model, we use the Strands Agents SDK’s structured output feature with Pydantic models to guarantee the response conforms to our schema:

from pydantic import BaseModel, Field
from strands import Agent
from strands.models import BedrockModel

class CommandSpec(BaseModel):
    name: str = Field(description="Command name in kebab-case")
    description: str = Field(description="What this command does")
    arguments: Optional[List[str]] = Field(default_factory=list)
    options: Optional[List[CommandOption]] = Field(default_factory=list)

class CLIRequirements(BaseModel):
    cli_name: str = Field(description="CLI name in kebab-case")
    description: str = Field(description="One-line description")
    commands: List[CommandSpec] = Field(description="Commands to generate")
    dependencies: List[str] = Field(default_factory=list)

# Create agent and invoke with structured output
agent = Agent(
    model=BedrockModel(model_id="us.anthropic.claude-opus-4-6-v1"),
    system_prompt="You are an expert CLI designer..."
)

result = agent(
    f"Analyze this CLI description: {description}",
    structured_output_model=CLIRequirements
)

# Access the validated Pydantic model — no JSON parsing needed
requirements: CLIRequirements = result.structured_output

By passing the structured_output_model, the Strands Agent constrains the model’s response to match the Pydantic schema. The result is a validated Python object where if the model’s first attempt does not conform to the schema, Strands automatically sends the validation errors back to the model and retries, producing a correct response without manual intervention. This approach eliminates malformed JSON, missing fields, wrong types, and hallucinated structure.

Role 2: Complete Command Generation with AI Functions

The second Amazon Bedrock role is generating complete command implementations. Direct integration of AI agents in code generation workflows is often avoided because of the model’s non-deterministic nature. There is no guarantee that generated code will compile, follow the expected structure, or avoid common pitfalls like empty error handlers. Strands AI Functions addresses this through runtime post-condition checking. AI Functions is a Python library for building reliable AI-powered applications through a new abstraction of functions that behave like standard Python functions but are evaluated by reasoning AI Agents. You decorate a function with @ai_function, write its prompt as a docstring with curly-brace placeholders, and attach post-conditions that the output must satisfy. If any post-condition fails, AI Functions automatically initiates a self-correcting loop, sending the specific error back to the model and retrying until all conditions pass or the maximum attempts are reached.

We use AI Functions to build a self-correcting code generation pipeline. Each generated command must pass three post-conditions before it is accepted:

from ai_functions import ai_function, PostConditionResult

def check_syntax(response: str) -> PostConditionResult:
    try:
        compile(response, '<generated>', 'exec')
        return PostConditionResult(passed=True)
    except SyntaxError as e:
        return PostConditionResult(
            passed=False,
            message=f"Python syntax error on line {e.lineno}: {e.msg}. Fix: {e.text}"
        )

def check_has_decorator(response: str) -> PostConditionResult:
    if '@cli.command' in response:
        return PostConditionResult(passed=True)
    return PostConditionResult(
        passed=False,
        message="Missing @cli.command() decorator."
    )

@ai_function(
    post_conditions=[check_syntax, check_has_decorator, check_no_empty_try],
    max_attempts=3
)
def generate_click_command(command_name: str, description: str, ...) -> str:
    """
    Generate a complete Click CLI command function in Python.

    Use @cli.command() decorator. Include needed imports using 'from X import Y' style.
    Always use 'import click' and reference as click.echo(), click.style().

    Command: {command_name}
    Description: {description}
    """

The @ai_function decorator turns the function’s docstring into a prompt template. Curly-brace placeholders like {command_name} are filled from the function arguments at call time. Each post-condition receives the model’s response and returns a PostConditionResult. When a condition fails, AI Functions sends the error message back to the model and retries automatically, up to max_attempts. The model sees the specific failure (“syntax error on line 42”, “missing @cli.command decorator”, “empty try/except block detected”) and corrects it on the next attempt.

The prompt embedded in the docstring still enforces coding conventions (use import click rather than from click import, use from X import Y for all other imports) to prevent import conflicts. Post-conditions catch what the prompt misses, making the pipeline significantly more reliable than prompt engineering alone.

MCP Server Discovery and Integration

The Model Context Protocol adds automatic discovery of external API knowledge to the pattern. When your tool description mentions AWS services, the system searches for MCP servers that can provide domain-specific tooling. Generated tools can tap into live, structured API knowledge beyond what Amazon Bedrock knows at generation time.

How Discovery Works

The system uses Amazon Bedrock to extract API keywords dynamically. The api_keywords field is part of the same CLIRequirements Pydantic model used for structured output, so keyword detection happens in the same call that extracts commands and dependencies at zero additional cost:

class CLIRequirements(BaseModel):
    cli_name: str = ...
    commands: List[CommandSpec] = ...
    dependencies: List[str] = ...
    api_keywords: List[str] = Field(
        default_factory=list,
        description="API/service keywords to search for MCP servers"
    )

When the model returns keywords like ["dynamodb", "s3", "cloudtrail"], the system uses a Strands Agent with the http_request tool from Strands Agents Tools to search the MCP registry for each keyword. Results are merged and deduplicated.

Interactive MCP Selection

After discovering relevant MCPs, the system presents them to the user for selection:

Terminal screenshot showing an AI-powered MCP server discovery process. The tool analyzes requirements, detects API keywords (DynamoDB, S3, CloudTrail), searches for relevant servers, and displays 18 available MCP servers in a numbered list. The user selects servers 1, 9, and 18 at a prompt, confirming the inclusion of AWS DynamoDB, AWS S3, and AWS CloudTrail.

Selected MCPs are configured in the generated CLI’s .mcp.json file, and a bridge module is copied to the output project. This bridge connects to MCP servers at runtime, extracts their tool metadata, and converts them into Strands @tool functions that the Agent can invoke.

Terminal screenshot showing CLI code generation in progress. The user confirms generation with "y." Command 1/5 (dynamo-capacity) succeeds with 9,181 characters generated. Command 2/5 (unused-buckets) fails validation due to a missing @cli.command() decorator, retries (attempt 1/3), and ultimately succeeds with 8,834 characters. Command 3/5 (audit-changes) begins generating.

After MCP selection, CLI Creator generates each command sequentially using AI Functions. Here, the unused-buckets command initially fails the check_has_decorator post-condition for missing the @cli.command decorator, and AI Functions automatically retries generation with the error fed back to the model, producing valid code on the second attempt. All commands go through this process before having an installable CLI.

The Meta-Tooling Workflow: Create, Update, Revert

The most distinctive feature of the pattern is the iterative tool refinement workflow. This is where meta-tooling becomes practical, and it is the part most easily adapted to domains beyond CLI generation.

Step 1: Install and verify the generated CLI

Terminal screenshot showing successful CLI tool generation. A green checkmark with green text confirms "CLI tool generated successfully!" A yellow warning notes "External dependencies detected!" followed by installation instructions: navigate to the generated/aws-ops-audit directory, install dependencies with pip, and verify with the --help command.

After generation completes, install the CLI and verify it works:

Terminal screenshot showing the help output for the "aws-ops-audit" CLI tool, run inside a Python virtual environment (test-venv). The tool is described as "An AWS operations reporter that checks DynamoDB capacity, lists unused S3 buckets, and audits CloudTrail changes." Two options (--version, --help) and six commands (audit-trail, check-capacity, configure, full-report, tool, unused-buckets) are listed.

Each command is fully implemented. Here is unused-buckets pulling live S3 data:

Terminal screenshot showing the output of the "aws-ops-audit unused-buckets" command run in a Python virtual environment. An "Unused S3 Buckets Report" lists four S3 buckets with metadata including name, region, object count, size, last modified date, creation date, and reason for being flagged — either "no activity since [date]" or "empty bucket."

After installation, the CLI is ready to use. Each subcommand supports --help for detailed parameter information.

Step 2: Create a new reporting tool at runtime

Consider a scenario where leadership requests a new report that was not part of the original CLI, such as a summary of all Amazon S3 buckets with their sizes, sorted by cost impact. Instead of modifying source code, use the built-in tool create command:

Terminal screenshot showing the output of the "aws-ops-audit unused-buckets" command run in a Python virtual environment. An "Unused S3 Buckets Report" lists four S3 buckets with metadata including name, region, object count, size, last modified date, creation date, and reason for being flagged — either "no activity since [date]" or "empty bucket."

Amazon Bedrock generates a complete Strands tool, saves it to `tools/`, and commits it to git. The next CLI command automatically discovers and loads the new tool from disk, so you can execute it right away:

Terminal screenshot showing the output of "aws-ops-audit tool execute list_s3_buckets_by_cost_impact." A summary section displays aggregate statistics for 26 S3 buckets totaling 3.99 GB and $1.10/year in estimated costs. Below, a detailed data table ranks all 26 buckets by cost impact, showing columns for bucket name, cost rank, cost tier (MINIMAL or EMPTY), creation date, estimated monthly/annual costs, object count, region, and size metrics.

Output is automatically formatted based on data type, so lists of dictionaries render as tables, single dictionaries display as key-value pairs, and everything else falls back to JSON.

Step 3: Update and review changes

Suppose the initial output needs adjustment. Leadership wants the report to exclude buckets with an object count of zero. The user describes this change in natural language using the tool update command.

Terminal screenshot showing the update of the "list_s3_buckets_by_cost_impact" tool using the aws-ops-audit CLI with the instruction to "exclude buckets with zero objects." The tool is updated via Bedrock AI analysis, versioned with git, and a git diff displays changes to the function's docstring — adding exclusion behavior documentation and new return fields (total_buckets_scanned, excluded_empty_buckets).

CLI Creator commits the current version to git before overwriting, then generates a new version. The tool diff command shows exactly what changed. Now execute the updated tool to see the improvements:

Terminal screenshot showing the updated output of "aws-ops-audit tool execute list_s3_buckets_by_cost_impact" after the zero-object exclusion update. Summary statistics now show 22 active buckets out of 26 scanned, with 4 empty buckets excluded. The data table lists only 22 rows, all classified as MINIMAL — confirming the empty bucket exclusion is working correctly.

The same update workflow applies regardless of what the tool does, whether it is an Amazon S3 cost report, an Amazon DynamoDB capacity analyzer, or a Salesforce data exporter.

Step 4: Revert if needed

If the update didn’t work as expected, tool revert restores the previous version from git:

Terminal screenshot showing the revert of the "list_s3_buckets_by_cost_impact" tool using the aws-ops-audit CLI. A confirmation prompt asks "Revert 'list_s3_buckets_by_cost_impact' to previous backup? [Y/n]:" and the user enters "y." A green checkmark confirms "Tool reverted!" followed by a note: "Restored from git history."

The git log shows the full history of create, update, and revert operations, all tracked automatically.

Terminal screenshot showing a two-line git log output. The most recent commit (ef4a65e, HEAD → main) reverts the list_s3_buckets_by_cost_impact tool. The previous commit (3640bde) updated the same tool to "exclude buckets with zero objects and add a total."

Under the hood, tool create, tool update, and tool revert are convenience wrappers around git. Each operation commits to the repository, so the version history is standard git and works with any existing workflow. The tool diff and tool revert commands exist so that someone iterating conversationally can see changes and undo them without switching context to git commands, but git log, git diff, and git revert work just as well. Git-based versioning and one-command reverts make it safe to experiment.

Step 5: Output formats

Reports often need to be consumed in different ways. The --format flag lets you control how output is rendered:

Terminal screenshot showing a two-line git log output. The most recent commit (ef4a65e, HEAD → main) reverts the list_s3_buckets_by_cost_impact tool. The previous commit (3640bde) updated the same tool to "exclude buckets with zero objects and add a total."

The formatter attempts to use the Rich library for colored tables when available and falls back to an ASCII table implementation when it is not installed. Here is a new AWS Lambda tool stored in `tools/`, rendering as a table by default:

Terminal screenshot showing the creation and immediate execution of a new "list_lambda_functions_by_code_size" tool using the aws-ops-audit CLI. The tool is created from a natural language description, then executed to produce a Lambda functions report for us-east-1 showing 11 functions with a total code size of 206.31 MB, displayed in a table sorted by code size descending.

IV. Conclusion

The meta-tooling pattern demonstrated here combines Amazon Bedrock for code generation, the Strands Agents SDK for runtime tool management, and Model Context Protocol for external API discovery into a system where CLIs extend themselves through natural language. The implementation has clear limitations today. Generated code still requires human review before production use; post-conditions catch structural errors but cannot verify business logic correctness, and the MCP ecosystem is young enough that server coverage is uneven across domains.

V. Next Steps

CLI tools are a natural starting point because they have a well-defined structure and fast feedback loops, but the same mechanism applies to any software that could benefit from generating and refining small, composable units of functionality at runtime. Infrastructure-as-code modules, data pipeline transformations, API integration adapters, and compliance policy checks are all domains where the creation pattern is repetitive, and the validation criteria are expressible as post-conditions. To explore the pattern:

– Start with Amazon Bedrock for foundation model access.

– Use the Strands Agents SDK for tool orchestration.

– Browse the MCP ecosystem at mcpservers.org.

– Fork the CLI Creator source code on GitHub.


About the authors

Ragib Ahsan

Ahsan is an AI Acceleration Architect at Amazon Web Services (AWS), where he helps organizations build and implement AI/ML solutions. Specializing in computer vision and industrial manufacturing, he works with AWS partners and engineering teams to create practical applications using cloud technologies.

Ensure Code Integrity for AWS Lambda Functions with Automated Code Signing Using Terraform

Post Syndicated from Sourav Kundu original https://aws.amazon.com/blogs/devops/ensure-code-integrity-for-aws-lambda-functions-with-automated-code-signing-using-terraform/

Authors: Sourav Kundu and Joyson Neville Lewis.

In today’s cloud-native landscape, ensuring the integrity and authenticity of your serverless functions is critical for maintaining security and compliance. Organizations face increasing challenges in preventing the execution of tampered or malicious code in their AWS Lambda functions. These challenges intensify as deployment pipelines become more complex and distributed.

AWS Lambda code signing provides a robust security mechanism that guarantees only trusted, unmodified code executes in your Lambda functions. By implementing digital signatures, you can verify code integrity and authenticate the source, creating a secure foundation for your serverless applications.

This post shows you how to implement AWS Lambda code signing using Terraform, creating an automated, end-to-end security framework that prevents unauthorized code execution while maintaining operational efficiency.

Solution overview

This solution creates a comprehensive code signing pipeline that automatically signs Lambda deployment packages and enforces signature validation at runtime. The implementation uses AWS Signer with the SHA384-ECDSA algorithm for cryptographic security, combined with Terraform automation for consistent deployments across environments.

Figure 1: Architecture diagram of AWS Lambda signing with AWS Signer

Figure 1: Architecture diagram of AWS Lambda signing with AWS Signer

The architecture includes:

AWS Signer: Creates signing profiles and jobs with strong cryptographic algorithms

Amazon S3: Stores original and signed Lambda code with versioning enabled

AWS Lambda: Deployed with code signing enforcement in a VPC environment

AWS KMS: Provides encryption for CloudWatch logs and SQS dead letter queue

VPC Configuration: Isolates Lambda execution in private subnets with VPC endpoints

Walkthrough

This walkthrough demonstrates how to deploy a secure Lambda function with code signing enabled using Terraform, a popular infrastructure as code.

The deployment process includes these key steps:

  1. Set up AWS Signer signing profile with cryptographic configuration
  2. Create S3 bucket with versioning for code storage
  3. Configure automated code signing jobs
  4. Secure Lambda deployment
  5. Implement security best practices including KMS encryption and VPC isolation
  6. Deploy the infrastructure with Terraform

Link to GitHub repository: AWS Lambda Code Signing with Terraform.

Prerequisites

For this walkthrough, you should have the following prerequisites:

– An AWS account with appropriate permissions for AWS Signer, Lambda, S3, and VPC services

– Terraform >= 1.0 installed on your local machine

– AWS CLI configured with credentials that have necessary service permissions

– Basic understanding of AWS Lambda, Terraform, and infrastructure as code concepts

1. Setup AWS Signer Signing Profile

The foundation of our code signing implementation starts with creating an AWS Signer signing profile. This profile is the identity that defines the cryptographic algorithm and signature validity period.

1.1 Define the signing profile resource in your Terraform configuration:

   resource "aws_signer_signing_profile" "lambda_signing_profile" {
     platform_id = "AWSLambda-SHA384-ECDSA"
     name        = "${replace(var.name, "-", "_")}_lambda_signing_profile_${random_string.suffix.result}"
     signature_validity_period {
       value = 135
       type  = "MONTHS"
     }
   }

We use the AWSLambda-SHA384-ECDSA platform, which provides strong cryptographic security with SHA-384 hashing and ECDSA (Elliptic Curve Digital Signature Algorithm).

1.2 Configure the code signing configuration that enforces security policies:

   resource "aws_lambda_code_signing_config" "configuration" {
     allowed_publishers {
       signing_profile_version_arns = [aws_signer_signing_profile.lambda_signing_profile.version_arn]
     }
     policies {
       untrusted_artifact_on_deployment = "Enforce"
     }
     description = "Code signing configuration for ${var.name} Lambda function."
   }

The untrusted_artifact_on_deployment = "Enforce" policy ensures that Lambda rejects any unsigned or improperly signed code.

2. Create S3 bucket with versioning for code storage

Before the code can be signed, it needs to be packaged and stored in a versioned S3 bucket. AWS Signer requires S3 versioning to uniquely identify the source artifact for each signing job.

2.1 Create the S3 bucket with versioning enabled:

resource "aws_s3_bucket" "lambda_source" {
  bucket        = "${var.name}-lambda-source-${data.aws_caller_identity.current.account_id}"
  force_destroy = true
}

resource "aws_s3_bucket_versioning" "lambda_source" {
  bucket = aws_s3_bucket.lambda_source.id
  versioning_configuration {
    status = "Enabled"
  }
}

Versioning is not optional here — AWS Signer uses the S3 object version_id to reference the exact artifact to sign.

2.2 Package the Lambda function code and upload it to the bucket:

data "archive_file" "python_file" {
  type        = "zip"
  source_dir  = "${path.module}/lambda_function/"
  output_path = "${path.module}/lambda_function/lambda_function.zip"
}

resource "aws_s3_object" "lambda_zip" {
  bucket     = aws_s3_bucket.lambda_source.bucket
  key        = "lambda_function.zip"
  source     = data.archive_file.python_file.output_path
  etag       = filemd5(data.archive_file.python_file.output_path)
  depends_on = [aws_s3_bucket_versioning.lambda_source]
}

The archive_file data source zips the contents of the lambda_function/ directory, and the aws_s3_object uploads it to the versioned bucket. The depends_on ensures versioning is active before the upload, so the object gets a version_id that the signing job can reference.

3. Configure automated Code Signing jobs

The next step creates an automated signing job that processes your Lambda code and generates signed artifacts.

3.1 Upload your Lambda code and configure the signing job:

   resource "aws_signer_signing_job" "build_signing_job" {
     profile_name = aws_signer_signing_profile.lambda_signing_profile.name

     source {
       s3 {
         bucket  = aws_s3_bucket.lambda_source.bucket
         key     = aws_s3_object.lambda_zip.key
         version = aws_s3_object.lambda_zip.version_id
       }
     }

     destination {
       s3 {
         bucket = aws_s3_bucket.lambda_source.bucket
         prefix = "signed/"
       }
     }
   }

This signing job automatically processes the uploaded Lambda code, creating a signed version stored in the signed/ prefix of your S3 bucket.

4. Secure Lambda Deployment

The Lambda function is configured to use the signed code and enforce code signing.

4.1 Deploy the Lambda function using the signed artifact:

resource "aws_lambda_function" "lambda_run" {
  s3_bucket        = aws_signer_signing_job.build_signing_job.signed_object[0].s3[0].bucket
  s3_key           = aws_signer_signing_job.build_signing_job.signed_object[0].s3[0].key
  source_code_hash = data.archive_file.python_file.output_base64sha256
  function_name    = var.name
  role             = aws_iam_role.lambda_role.arn
  handler          = "handler.lambda_handler"
  runtime          = "python3.12"
  
  code_signing_config_arn = aws_lambda_code_signing_config.configuration.arn
  
  kms_key_arn = aws_kms_key.encryption.arn
  vpc_config {
    subnet_ids         = aws_subnet.private[*].id
    security_group_ids = [aws_security_group.lambda.id]
  }
  tracing_config {
    mode = "Active"
  }
  dead_letter_config {
    target_arn = aws_sqs_queue.dlq.arn
  }
}

The s3_bucket and s3_key reference the signed artifact produced by the signing job. Terraform resolves aws_signer_signing_job.build_signing_job.signed_object[0].s3[0] to the output location where AWS Signer wrote the signed package in step 3. This ensures Lambda always deploys the signed version, never the unsigned source.

The code_signing_config_arn ties the Lambda function to the code signing configuration from step 1. At deploy time, Lambda validates the artifact’s signature against the allowed publishers in that configuration. If the signature is missing, expired, or from an untrusted profile, the deployment is rejected.

5. Implement Security Best Practices

This implementation includes additional security layers beyond code signing to create a comprehensive security framework.

5.1 Create a KMS key with automatic key rotation and a least-privilege policy:

resource "aws_kms_key" "encryption" {
  enable_key_rotation     = true
  description             = "Key to encrypt all the cloud resources in ${var.name}."
  deletion_window_in_days = var.deletion_window_in_days
}

data "aws_iam_policy_document" "encryption_policy" {
  statement {
    sid    = "Enable IAM User Permissions"
    effect = "Allow"
    principals {
      type        = "AWS"
      identifiers = ["arn:aws:iam::${data.aws_caller_identity.current.account_id}:root"]
    }
    actions = [
      "kms:Encrypt", "kms:Decrypt", "kms:ReEncrypt*",
      "kms:GenerateDataKey*", "kms:DescribeKey",
      "kms:Create*", "kms:Enable*", "kms:List*",
      "kms:Put*", "kms:Update*", "kms:Revoke*",
      "kms:Disable*", "kms:Get*", "kms:Delete*",
      "kms:ScheduleKeyDeletion", "kms:CancelKeyDeletion",
      "kms:TagResource", "kms:UntagResource"
    ]
    resources = [aws_kms_key.encryption.arn]
  }
  statement {
    sid    = "Allow CloudWatch to use the key"
    effect = "Allow"
    principals {
      type        = "Service"
      identifiers = ["logs.amazonaws.com"]
    }
    actions = [
      "kms:Encrypt", "kms:Decrypt", "kms:ReEncrypt*",
      "kms:GenerateDataKey*", "kms:DescribeKey", "kms:CreateGrant"
    ]
    resources = [aws_kms_key.encryption.arn]
    condition {
      test     = "ArnEquals"
      variable = "kms:EncryptionContext:aws:logs:arn"
      values   = [local.cloudwatch_log_group_arn]
    }
  }
  statement {
    sid    = "Allow Lambda to use the key"
    effect = "Allow"
    principals {
      type        = "Service"
      identifiers = ["lambda.amazonaws.com"]
    }
    actions = [
      "kms:Encrypt", "kms:Decrypt", "kms:ReEncrypt*",
      "kms:GenerateDataKey*", "kms:DescribeKey", "kms:CreateGrant"
    ]
    resources = [aws_kms_key.encryption.arn]
    condition {
      test     = "StringEquals"
      variable = "kms:EncryptionContext:LambdaFunctionName"
      values   = [var.name]
    }
    condition {
      test     = "StringEquals"
      variable = "aws:RequestedRegion"
      values   = [var.region]
    }
  }
}

resource "aws_kms_key_policy" "encryption" {
  key_id = aws_kms_key.encryption.id
  policy = data.aws_iam_policy_document.encryption_policy.json
}

The enable_key_rotation = true setting enables automatic annual key rotation, a recommended security practice. The policy uses aws_iam_policy_document instead of inline JSON for better readability and validation. Each statement is scoped to a specific principal: the root account gets administrative access with enumerated actions (not kms:*), CloudWatch Logs can only use the key for the specific log group via the kms:EncryptionContext:aws:logs:arn condition, and Lambda access is constrained to the specific function name and region. This ensures no service can use the key beyond its intended scope.

5.2 Configure VPC with private subnets for Lambda isolation:

resource "aws_vpc" "main" {
  cidr_block           = var.vpc_cidr
  enable_dns_hostnames = true
  enable_dns_support   = true
}

resource "aws_subnet" "private" {
  count             = length(var.subnet_cidr_private)
  vpc_id            = aws_vpc.main.id
  cidr_block        = var.subnet_cidr_private[count.index]
  availability_zone = data.aws_availability_zones.available.names[count.index]
}

The enable_dns_hostnames and enable_dns_support settings are required for VPC endpoints to resolve via private DNS.

5.3 Add VPC endpoints so the Lambda function can reach CloudWatch Logs and SQS from the private subnets without internet access:

resource "aws_vpc_endpoint" "logs" {
  vpc_id              = aws_vpc.main.id
  service_name        = "com.amazonaws.${var.region}.logs"
  vpc_endpoint_type   = "Interface"
  subnet_ids          = aws_subnet.private[*].id
  security_group_ids  = [aws_security_group.endpoint_sg.id]
  private_dns_enabled = true
}

resource "aws_vpc_endpoint" "sqs" {
  vpc_id              = aws_vpc.main.id
  service_name        = "com.amazonaws.${var.region}.sqs"
  vpc_endpoint_type   = "Interface"
  subnet_ids          = aws_subnet.private[*].id
  security_group_ids  = [aws_security_group.endpoint_sg.id]
  private_dns_enabled = true
}

The Lambda function uses an SQS dead letter queue and hence requires the SQS endpoint. The private_dns_enabled setting allows the Lambda function to reach these services using their standard endpoints without any code changes. For the complete networking configuration including security groups and route tables, see the GitHub repository.

These security measures create defense in depth, combining code signing with encryption, network isolation, and secure communication channels.

6. Deploy the Infrastructure

With all the resources defined, initialize and deploy the complete infrastructure:

terraform init
terraform plan
terraform apply

The terraform init command downloads the required providers. The terraform plan command previews all the resources that will be created, and terraform apply provisions the entire stack — signing profile, S3 bucket, signing job, Lambda function, and all supporting infrastructure — in the correct dependency order.

Verification

After the deployment completes, verify that the signing profile, signing job, and Lambda code signing configuration are correctly set up.

Verify the signing profile is active:

aws signer list-signing-profiles --query "profiles[].{Name:profileName,Status:status}" --output table

Confirm the signing job completed successfully:

aws signer list-signing-jobs --status Succeeded --query "jobs[0].{JobId:jobId,Status:status,SignedObject:signedObject}" --output table

Verify the Lambda function has code signing enforced:

aws lambda get-function-code-signing-config --function-name <YOUR-FUNCTION-NAME> --query "{CodeSigningConfigArn:CodeSigningConfigArn}" --output table

Each command should return results confirming the resources are active and properly configured. If any command returns empty results, review the Terraform output for errors during deployment.

Cleaning Up

To avoid incurring future charges, delete the resources created in this walkthrough using the command:

terraform destroy

This command removes all resources including the Lambda function, S3 bucket, VPC components, and KMS keys. This command also deletes the signing profile and code signing configuration.

Conclusion

In this post, you learned how to implement AWS Lambda code signing using Terraform to create a secure, automated deployment pipeline. This solution ensures code integrity, prevents unauthorized modifications, and helps meet compliance requirements while maintaining operational efficiency through infrastructure as code.

The implementation demonstrates defense-in-depth security practices including cryptographic signing, encryption at rest, network isolation, and comprehensive monitoring. By automating the entire process with Terraform, you can consistently deploy secure Lambda functions across multiple environments and maintain security standards at scale.

For more information about AWS Lambda security best practices, see the AWS Lambda Developer Guide. To learn more about AWS Signer, visit the AWS Signer Developer Guide.


About the authors

Sourav Kundu

Sourav is a seasoned DevOps Consultant who specializes in helping organizations securely migrate to and efficiently build on the AWS cloud using modern software engineering practices. He believes that democratizing cloud knowledge is essential for driving innovation and is committed to helping others succeed in their cloud journey.

Joyson Neville Lewis

Joyson is a Sr. Conversational AI Architect with AWS Professional Services. Joyson worked as a Software/Data engineer before diving into the Conversational AI and Industrial IoT space. He assists AWS customers to materialize AI outcomes using Voice Assistant/Chatbot and IoT solutions.

Building an end-to-end agentic SRE using AWS DevOps Agent

Post Syndicated from Ray Hodges original https://aws.amazon.com/blogs/devops/building-an-end-to-end-agentic-sre-using-aws-devops-agent/

Introduction

As modern applications evolve into complex ecosystems of serverless functions, microservices, and event-driven architectures, incident response becomes increasingly challenging. DevOps and SRE teams spend hours manually correlating data across observability tools and troubleshooting issues, racing against SLA deadlines. This reactive firefighting drains productivity, degrades reliability, and delays innovation.

AWS DevOps Agent provides an opportunity to shift how teams achieve operational excellence. As an autonomous, always-on frontier agent, it investigates incidents the moment they occur, identifies root causes by correlating telemetry across your ecosystem, and recommends specific mitigation plans, all without constant human intervention. On-call engineers wake up to a root cause, instead of active incidents. AWS DevOps Agent supports multi-cloud and hybrid environments, not just AWS-native architectures.

This blog post demonstrates how to build an end-to-end agentic SRE solution using AWS DevOps Agent. You learn how to configure DevOps Agent Spaces that define an investigation scope, integrating seamlessly with Amazon CloudWatch, Splunk, GitHub, and Slack. It further demonstrates automated incident trigger using webhooks, and AWS DevOps Agent integration with custom tools by creating a custom MCP agent. The agent investigates issues by analyzing patterns across multiple data sources, providing root cause, and then generates detailed mitigation plans that can be implemented via a coding agent. By the end, you will have a deployed frontier agent that acts as a true extension of your team. One that works persistently, scales massively, and delivers complete operational outcomes while freeing your engineers to focus on innovation rather than firefighting.

Architecture

Architectural diagram showing the setup used in this AWS DevOps Agent deployment.

Implementation

This implementation spans three specialized AWS accounts with distinct responsibilities.

The Demo Application account hosts the production infrastructure being monitored. The CI/CD pipeline integrates GitHub via AWS CodePipeline for automated deployments, while an Application Load Balancer distributes traffic and monitors health. The observability layer leverages Amazon CloudWatch alarms to detect anomalies, Amazon EventBridge to route events, and AWS Lambda as a webhook handler that forwards incident notifications to AWS DevOps Agent.

The account named Splunk provides centralized log aggregation and analysis. An Amazon EC2 instance hosts the Splunk Log Collector, while Splunk MCP manages the centralized control plane. A VPC peering connection establishes secure, private network connectivity between the Demo Application and Splunk account VPCs, enabling seamless log forwarding, without internet exposure.

AWS DevOps Agent account contains the autonomous investigation engine. AWS DevOps Agent receives incident webhooks from the Demo Application account, orchestrates autonomous investigations across integrated data sources, correlates telemetry from CloudWatch, Splunk, and GitHub, generates mitigation plans, and coordinates the incident response. The webhook integration provides communication, receiving incident triggers from Lambda, and sending investigation updates to Slack for real-time team collaboration.

Data flow: When an incident triggers the CloudWatch alarm, EventBridge invokes a Lambda function that, in turn, invokes the DevOps Agent webhook with a payload. The agent triggers an investigation based on its native troubleshooting capabilities. For a comprehensive view of the incident, it queries Splunk logs via MCP, retrieves deployment history from GitHub, and correlates CloudWatch metrics with deployment events to build application topology understanding. It analyzes temporal relationships between deployments and operational incidents, identifies root causes, and generates detailed mitigation plans with specific remediation steps, success criteria, and rollback procedures via Splunk MCP. The DevOps Agent’s runbooks/skills guide its investigation from start to finish, keeping it on track and aligned with established SRE procedures. Investigation results and recommendations are posted to Slack, enabling on-call engineers to wake up to identified root cause, instead of active incidents.

Creating your agentic DevOps engineer

DevOps Agent Spaces

A DevOps Agent Space defines the tools and infrastructure that AWS DevOps Agent has access to. Each Agent Space contains your AWS account configurations, third-party tool integrations, and access permissions. See Best Practices for Deploying AWS DevOps Agent in Production for detailed information describing the DevOps Agent spaces.

Creating an Agent Space can be done through the console, or via AWS Command Line Interface (AWS CLI). You should name your Agent Space with a descriptive name to identify its purpose. For example, if your application is “WidgetMaker”, then you can name your Agent Space “WidgetMaker Agent” to help you quickly identify the context of that agent.

Follow the steps in Creating an Agent Space for details and considerations when creating an Agent Space.

Agent Space webhooks

Before connecting any services to your DevOps Agent Space, make sure to create the webhook for your Agent Space. The schema for you to send messages to your Agent Space is shown below:

{ 
eventType: ‘incident’; 
incidentId: string; 
action: ‘created’ | ‘updated’ | ‘closed’ | ‘resolved’; 
priority: “CRITICAL” | “HIGH” | “MEDIUM” | “LOW” | “MIMIMAL”; 
title: string; 
description?: string; 
timestamp?: string; 
service?: string; 
//The original event generated by service is attached here. 
data?: object; 
}

You can find great examples on the Invoking DevOps Agent through Webhook page. When creating a secure connection for this blog, we used HMAC (Hashbased Message Authorization Code). Optionally, you can experiment with the CloudWatch Alarm Webhook Integration from Git.

{
import { createHmac } from "node:crypto"; 
function sendEventToWebhook() { 
   const payload = { 
      eventType: "incident", 
      ... // other event data 
    }; 
const timestamp = new Date().toISOString(); 
const hmac = createHmac("sha256", secret); 
hmac.update(`${timestamp}:${JSON.stringify(payload)}`, "utf8"); 
const signature = hmac.digest("base64"); 
fetch(webhookUrl, { 
   method: "POST", 
   headers: { 
      "Content-Type": "application/json", 
      "x-amzn-event-timestamp": timestamp, 
      "x-amzn-event-signature": signature, 
    }, 
    body: JSON.stringify(payload), 
  }); 
}

Finally, you create the webhook.

Screenshot of the "Create a webhook to trigger investigations for your agent space" form.

Make sure you download and save this unique url and secret key. Once you move on from this screen, you will no longer be able to see the secret. Now that we’ve created the webhook endpoint, we will set up the alarm or choose an existing alarm. Then we will use an Amazon Simple Notification Service (Amazon SNS) topic as the Alarm Action and subscribe a Lambda function to this topic. The Lambda function then calls the webhook. Store the webhook URL in Lambda environment variables for security.

The CloudWatch flow is: CloudWatch Alarm → Amazon EventBridge → Lambda → DevOps Agent Webhook.

Test by forcing the alarm into the ALARM state and verifying the DevOps Agent receives the event. See some samples on sending these alarms via WebHook at the aws-samples github.

Splunk Integration

For Splunk integration, you will need to perform a few tasks on your Splunk server. First, you will need to enable the Splunk MCP Server to expose the MCP URL for AWS DevOps Agent.

For Splunk MCP Server, you will first configure a token to allow AWS DevOps Agent to securely log into the Splunk MCP server.

Note: You will need to have a role called ‘mcp_user’ (it doesn’t need any capabilities) and add it to the user account in Splunk that you are going to create the token in the next step.

Screenshot of Splunk MCP Server configuration form.

The audience should default to ‘mcp’ on this screen, but if not, audience will need to be ‘mcp’. Remember, you must copy the token from the screen when you create the token, or you will not be able to access it after you close the screen, requiring you to create a new token. Then, you can validate that the endpoint is active and copy the endpoint url. Note, the url presented reflects the url that you are using for the Splunk management console. If you have created a listener on port 8089 with a different url, for example, https://splunkmcp.yoururl.com:8089, then you will need to replace the url shown (https://splunkadmin.yoururl.com) with the proper url.

Screenshot showing Splunk's MCP Server endpoint.

Finally, copy the MCP Configuration for use in AWS DevOps Agent. Note, just as above, validate that the url is the same as the listener you have created. Also, reminder to replace <Your Token> with the bearer token you’ve created (and copied) above.

Screenshot showing Splunk MCP configuration.

To configure Splunk to send alerts to AWS DevOps Agent to begin investigations, you will need to use Better Webhooks because the default Splunk webhook does not support headers nor authentication.

Once you have Better Webhooks, you can create a credential and choose Custom HTTP Header. Name can be whatever you desire, but we used “DevOpsAgentBearer” to be descriptive.

Header Name: Authorization

Header Value: “Bearer thetokenyousavedwhenyoucreateddevopsagentwebhook”
(Include “Bearer” and a space before your token from your DevOps Agent webhook)

Screenshot showing Splunk's A Better Webhooks credential configuration form.

You can skip the advanced section and save your credential.

Now, you can configure the alert for your error state by finding it in search and saving search as an alert. Under Trigger Actions, select Add Actions and choose Better Webhook from the menu.

Screenshot showing the creation of an alert in Splunk.

Then, format the message body as shown in AWS DevOps Agent.

{ eventType: ‘incident’; 
incidentId: string; 
action: ‘created’ | ‘updated’ | ‘closed’ | ‘resolved’; 
priority: “CRITICAL” | “HIGH” | “MEDIUM” | “LOW” | “MIMIMAL”; 
title: string; 
description?: string; 
timestamp?: string; 
service?: string; 
//The original event generated by service is attached here. 
data?: object; 
}

In Splunk, the URL is the DevOps Agent webhook url which you had saved in a .csv with your token while creating the webhook. Paste the format above into the Body Format section as shown below, select the credential you saved in Better Webhooks earlier, and save your alert.

Screenshot showing formatting the body of your alerts from Splunk to DevOps Agent in the Splunk alerts form.

Notice that the Body Format box should reflect the format from AWS DevOps Agent above. Now, AWS DevOps Agent will initiate an investigation when Splunk errors exceed the threshold for the alert you’ve created. You may want to experiment with throttling and thresholds to keep AWS DevOps Agent from starting too many investigations.

Connecting to Slack

You can connect AWS DevOps Agent to your Slack environment and configure a channel for your Agent Space to communicate with. You can have multiple Agent Spaces communicate in one Slack channel, or you can have existing Slack channels for your SRE team invite the Agent Space to it.

To get started, you need to have access to a Slack workspace with the ability to install and authorize third-party applications. You then need to go to the AWS DevOps Agent console, navigate to “Settings” and select “Communications”. When you choose Register, you will be redirected to Slack to authorize the AWS DevOps Agent application for your workspace. It is important to install at the workspace level, not in your enterprise grid.

After you choose Allow, you will be directed back to your DevOps Agent console to associate your Agent Space with your Slack channel. Go to your Agent Space, scroll down to Communications, and choose Add integration.

Screenshot showing the configuration of communication in DevOps Agent.

Towards the bottom of the popup, you should see Slack and it should show “Registered” in green.

Screenshot showing Slack being registered in DevOps Agent.

Choose Add and follow the instructions in the window to obtain and insert your channel ID into the DevOps Agent Space.

Screenshot showing how to connect an Agent Space Slack.

Once completed, you just need to add the AWS DevOps Agent to your channel by typing the following into your Slack channel: /invite @AWS DevOps Agent

Now, you can start an investigation, and the AWS DevOps Agent will provide details in your channel.

Connecting GitHub to AWS DevOps Agent

Screenshot showing the configuration screen in DevOps Agent to connect to GitHub.

Screenshot with further details to configure your GitHub connection in DevOps Agent.

GitHub integration is a two-step process. First, register GitHub at the AWS account level: navigate to your Agent Space’s Capabilities tab, select Add under Pipeline, choose GitHub, and complete the OAuth flow to install the AWS DevOps Agent GitHub app. You can select which repositories the app can access — all or a specific subset. Once registered, connect repositories to individual Agent Spaces by selecting the relevant repos under the Pipeline section. The GitHub app requests read-only access and receive deployment events, enabling the agent to correlate code changes with operational incidents.

DevOps Agent Skills

You can use DevOps Agent Skills to define a set of rules for all investigations to follow, guiding the Agent to use certain documentation, or telemetry sources for certain types of data. Skills are self-contained directories containing Markdown instructions that provide specialized capabilities to AWS DevOps Agent. AWS DevOps Agent supports a subset of the Agent Skills specification — an open standard for packaging agent instructions and resources—supporting only non-executable documents: Markdown instructions, PDFs, images, and data files. For example, if your environment uses Dynatrace for alarms and metrics, Splunk for logs, and CloudWatch for serverless logs, create a skill to accelerate issue resolution. You create these Skills in your Operator console by selecting the Skills section on the lower left side of the screen. You can then either review your existing skills or use the Add skill button to choose between Create skill and Upload skill options.

Screenshot showing the Skills definition page in the DevOps Agent Operator console.

The documentation on DevOps Agent Skills should help you with the schema and best practices in creating these skills.

Investigate root cause

Now that you have everything connected to your DevOps Agent Space, you can interact with the AWS DevOps Agent you’ve created. You can investigate anomalies in your environment, or have alarms trigger your Agent to begin an investigation on its own and provide updates in your Slack channel and the Operator console. You can also ask the agent to provide health summaries, suggest preventive maintenance, and other SRE tasks you would do throughout the lifecycle. You can do this in the operator console and simply type your question into the Chat with DevOps Agent box. For example, “What is causing high CPU usage on my EC2 instances starting an hour ago?” and the AWS DevOps Agent will begin investigating your request.

Screenshot of the DevOps Agent Operator Console to initiate a chat with a DevOps Agent.

While optional, the steps below can help speed up a particular investigation and help track multiple investigations. Adding an Investigation starting point can help speed up the investigation by telling the agent to check a particular alarm, or an Autoscaling Group (ASG), or even a specific set of instances where you are seeing increased CPU usage. This guides the investigation to start with data sources pertaining to these resources, instead of looking at all your telemetry to find anomalies to start investigating.

Screenshot showing the Investigation starting point text box to help guide an investigation in DevOps Agent.

You should also make a habit of assigning a meaningful name to your investigations, so that you can look at the historical data with some context.

Screenshot showing the Name your investigation input in DevOps Agent Operator Console.

Generating mitigation plan

A mitigation plan is a set of actionable steps that AWS DevOps Agent produces to resolve an identified incident. After the agent publishes a root cause under the Root Cause tab, select “Generate mitigation plan” to create a structured remediation plan. Alternatively, automate this step using the AWS CLI — use aws devopsagent create-backlog-task to trigger investigations and update-backlog-task to approve mitigation plans programmatically. By automating this step, you can integrate mitigation plan generation directly within their incident workflow, without having to leave their incident management application. The CLI returns the mitigation steps back into the integrated app or system. Each plan follows four phases: Prepare, Pre-Validate, Apply, and Post-Validate. Within each phase, the agent provides suggested actions with commands to update infrastructure-as-code templates or make configuration changes. It also generates agent-ready specs compatible with coding agents like Kiro for implementation.

Screenshot showing the "Generate mitigation plan" button in DevOps Agent Operator Console.

Agent-ready Spec and fix implementation

An agent-ready spec is a structured set of instructions that AWS DevOps Agent generates within a mitigation plan, designed to be consumed directly by a coding agent. When the mitigation plan includes code-level fixes — such as updating infrastructure-as-code templates or application logic — AWS DevOps Agent produces these specs alongside the suggested actions. To apply a fix, copy the agent-ready spec and hand it off to a compatible coding agent like Kiro. The coding agent interprets the spec and implements the required changes in your codebase. This creates a seamless handoff from incident diagnosis to code remediation, closing the loop between identifying a root cause and deploying the fix without manually translating mitigation steps into code changes.

Screenshot showing the "Agent-ready spec" screen in DevOps Agent console.

Conclusion

In this post, we demonstrated building an end-to-end agentic SRE solution using AWS DevOps Agent — from configuring Agent Spaces and integrating CloudWatch, Splunk, GitHub, and Slack, to triggering automated investigations via webhooks, generating mitigation plans, and handing off agent-ready specs to coding agents like Kiro for implementation. Together, these capabilities shift incident response from reactive firefighting to autonomous resolution, reducing MTTR from hours to minutes while freeing your engineers to focus on innovation.

Get started today:

Author Bios

Photo of Manik Chopra, one of the authors

Manik Chopra

Manik Chopra is a Principal Technical Account Manager at AWS. He helps customers adopt AWS services and provides guidance in various areas around Generative AI, Data Analytics and Optimization. His areas of expertise include delivering solutions using Amazon Bedrock, AWS DevOps Agent, Amazon QuickSight, Amazon Athena, and various other automation techniques. Outside of work, he enjoys spending time outdoors and traveling.

Photo of Ray Hodges, one of the authors

Ray Hodges

Ray Hodges is a Senior Technical Account Manager at Amazon Web Services, where he’s been guiding some of the world’s largest enterprises through their cloud journeys. Ray partners with Fortune 100 customers — most notably, a large financial institution — to drive transformative outcomes in operational resilience, observability modernization, and enterprise-scale cloud operations. Ray leads many operations and resiliency efforts. Prior to AWS, Ray built 25+ years of enterprise IT expertise as an Enterprise Architect at Atos and Senior Architect at IBM, where he led large-scale private cloud implementations and pioneered PaaS delivery models. He is an AWS Certified Solutions Architect Professional, and brings deep cross-domain expertise spanning architecture, security, operations, and service management — all with a relentless focus on driving resilient business outcomes through technology.

Photo of Sheng Liao, one of the authors

Sheng Liao

Sheng Liao is Sr. TAM Manager at Amazon Web Services, where she leads a team of Technical Account Managers dedicated to AWS’s largest and most complex strategic accounts. With a focus on cloud operations, AI/ML adoption, and enterprise architecture, Sheng works closely with senior technical leaders to accelerate cloud transformation at scale. Her team has driven impactful outcomes including GenAI-powered analytics in production processing millions of transactions monthly, early adoption of autonomous DevOps tooling that reduced incident response times to minutes, and large-scale observability modernization initiatives. Sheng is a strong advocate for bringing AWS thought leadership directly to customers, championing programs like AI/ML Developer Lifecycle sessions that have engaged hundreds of engineers and architects. Prior to her current role, Sheng built extensive experience across cloud infrastructure and enterprise technology.

AWS Transform custom: Enterprise Code Modernization with the Learn-Scale-Improve Flywheel

Post Syndicated from Venugopalan Vasudevan original https://aws.amazon.com/blogs/devops/aws-transform-custom-enterprise-code-modernization-with-the-learn-scale-improve-flywheel/

Enterprise modernization has reached an inflection point. You can transform one repository easily. Existing tools, including AWS Transform custom, work well for individual repositories, and the process is understood. But what about 50 repositories? 100? 200? When you need to modernize at enterprise scale, transforming code is only part of the challenge. Coordinating people, capturing knowledge, and maintaining quality across your entire portfolio are also important.

In this post, we explore how AWS Transform custom’s bulk automation capabilities address the enterprise coordination problem through intelligent learning and scaled execution. You will see how one customer reduced end-to-end modernization timelines from 7-12 weeks to 2.5 weeks, delivering a 3-5x reduction in delivery time and 10-20x reduction in total effort hours. Most importantly, you will learn how to start your own transformation journey immediately.

The Coordination Problem at Enterprise Scale

Ask any enterprise architect about their last major modernization initiative, and you will hear familiar stories. As an example, an enterprise software company needed to migrate a large legacy codebase to a modern platform. Their projection: 12 weeks of intensive work coordinating across multiple teams.

The code transformation itself took days. The remaining weeks were consumed by the end-to-end activities surrounding it: orchestrating teams across time zones, ensuring consistent patterns across codebases with different histories, and managing dependencies so upstream changes did not break downstream systems. Teams tracked status through meetings and spreadsheets and captured tribal knowledge that existed only in senior developer heads.

This is the enterprise coordination problem. When you scale from one repository to hundreds, coordination overhead explodes. Each additional repository adds not just its own complexity, but new integration points, edge cases, and unanticipated coordination requirements.

The Hidden 70% Gap

In enterprise engagements, we have observed that code transformation represents approximately 30% of the modernization effort. The remaining 70% include things like test generation, validation, comprehensive documentation, business analysis, and organizational coordination across hundreds of moving pieces.

This gap explains why productivity gains from transformation tools rarely materialize. The tools handle code changes, but organizations still struggle with coordination, validation, and knowledge capture. The transformation is completed quickly, but the project takes months.

Here is what we see: traditional approaches fail at enterprise scale because they treat each repository as an independent challenge. Teams repeat work across codebases, make inconsistent decisions, and lose learnings when developers move to different projects. Organizational knowledge remains trapped in individual heads rather than becoming reusable assets.

A New Approach to Enterprise Modernization

AWS Transform custom takes a different approach to enterprise modernization. Rather than repeating the same operation hundreds of times, the service learns from every execution and applies that knowledge to improve future transformations.

The Learn-Scale-Improve Flywheel

The workflow follows a deliberate progression designed to maximize learning while minimizing risk. It begins with a focused learn pilot, scales through bulk automation, and improves through deliberate review, creating a flywheel where each cycle produces better results than the last (Figure 1).

Iterative transformation workflow with three stages: LEARN (interactive pilot, refine TD), SCALE (bulk execution, overnight processing), and IMPROVE (review and approve knowledge items). Arrows show the cycle: org knowledge captured flows from Learn to Scale, edge cases observed flow from Scale to Improve, and TD improves flows from Improve back to Learn.

Figure 1: Learn Scale and Improve Flywheel for AWS Transform custom transformation

Learn — You start with two to three representative repositories and execute transformations in interactive mode. You work directly with the AI agent, providing feedback on decisions and validating quality at each step. When the agent encounters ambiguity, it asks questions. You provide guidance, and the system captures that context. At the end of the pilot, you review the feedback and modify the transformation definition. The result is a transformation definition enhanced with your organizational knowledge, ready to scale.

Scale — You shift to non-interactive mode for bulk execution. The system processes dozens or hundreds of repositories overnight without manual intervention, applying patterns learned during the pilot. It validates transformations using your build and test commands and tracks progress across your portfolio in real time. What previously required weeks of team coordination happens overnight. During execution, the system captures observations: new edge cases, unexpected patterns, and optimization opportunities the pilot did not encounter.

Improve — After each round of bulk execution, you review the knowledge items the system captured during processing. These observations surface patterns and edge cases specific to repositories the pilot did not cover. You approve the valuable learnings, and your transformation definition improves for the next iteration. This review step ensures quality control. The system does not self-modify. Transformation owners decide which learnings get incorporated.

The Scale-Improve cycle repeats. Each round of bulk execution generates insights that make the next round more effective. Transformation success rates increase, manual intervention decreases, and edge case handling improves with every iteration.

This flywheel transforms how enterprises capture and share institutional knowledge. Transformation definitions are not automation scripts. They are organizational assets that encode how your company approaches specific modernization scenarios. When an architect defines a transformation strategy, that strategy becomes a reusable definition stored in your registry. When your team identifies best practices, those practices become embedded within the transformation definition and automatically apply across all repositories. Previously, when a senior developer left your team, that knowledge disappears with them. With AWS Transform custom, their expertise is captured in transformation definitions and knowledge items available to the entire organization. Individual expertise becomes an organizational capability.

An Enterprise Customer Modernization Case Study

These productivity gains are production outcomes, not theoretical projections. An enterprise software company needed to migrate a large volume of production-grade Control-M workflows to Apache Airflow, a modernization requiring both technical precision and consistency across a complex, interdependent codebase. Their estimate was 12 weeks of intensive coordination across multiple teams, with risk of inconsistency and integration failures.

Using AWS Transform custom, the company executed an iterative learn-scale-improve workflow. During the pilot phase, they ran interactive transformations on representative repositories, reviewed results, and refined transformation definitions. With each iteration, transformation definitions improved in edge case handling and accuracy. They then shifted to non-interactive bulk execution across their portfolio and completed the full migration in 2.5 weeks.

The validation achieved a 100% success rate across all workflows in scope. Edge case handling improved by 60% compared to the customer’s existing approach, and the transformed code demonstrated a 19% runtime performance improvement while meeting industry expert code quality standards. This proves that organizations can achieve both migration speed and production readiness, with 3-5x faster delivery timelines and 10-20x reduction in total effort hours compared to traditional approaches.

Get Started: Transform Your Repository Portfolio

AWS Transform custom bulk automation capabilities are available as a solution in this Github repo. Follow the learn-scale-improve workflow to begin your transformation journey.

Prerequisites

Before beginning, ensure you have:

  • An AWS account with AWS Transform custom access enabled
  • AWS CLI configured with appropriate credentials
  • Git installed on your local machine or CI/CD environment
  • IAM permissions for AWS Transform custom operations

Your Implementation Path

AWS Transform custom supports Java upgrades (e.g., 8 to 17, 17 to 21), Python migrations (e.g., 3.7 to 3.11), Node.js updates (e.g., 14 to 20), AWS SDK migrations (e.g., boto2 to boto3, SDK v1 to v2), and other transformations. Beyond these AWS-managed transformations, you can create custom transformation definitions for organization-specific standards, proprietary framework migrations, and architectural patterns unique to your environment.

AWS Transform custom integrates naturally into your existing development processes. The CLI connects with CI/CD pipelines like Jenkins, GitLab CI, or GitHub Actions. Transformations create code in local Git branches that flow through your standard code review and merge processes. The web interface provides centralized visibility for tracking progress across teams. Validation commands execute automatically during transformation, ensuring code builds successfully and tests pass before changes are considered complete. At the end of the transformation, if validation criteria fail, the transformation is marked as failed.

To accelerate your path to scaled execution, AWS provides an open-source sample repository that gives you a production-ready starting point for running transformations across multiple repositories and transformation definitions simultaneously. The aws-transform-custom-samples scaled execution repository includes scripts that orchestrate bulk execution, manage repository queuing, and handle status tracking across your portfolio. Rather than building orchestration from scratch, you clone the sample, configure it with your repository list and transformation definitions, and begin executing scaled transformations immediately.

Conclusion

Enterprise modernization at scale requires more than code transformation tools. The real challenges are coordination across teams, learning from execution, and capturing knowledge as organizational assets. AWS Transform custom learn-scale-improve workflow addresses these challenges through continual learning that improves quality with every execution, organizational knowledge capture that transforms tribal expertise into reusable assets, and bulk automation that scales consistently across hundreds of repositories. When the next critical security vulnerability requires framework updates across your repositories, or a new runtime version unlocks performance improvements, you respond in days rather than months — using transformation definitions you have already proven.

Real customers have reduced delivery timelines by 3-5x and total effort hours by 10-20x, compressing modernization from months to weeks. These are not aspirational goals. They are production results from organizations using AWS Transform custom today.

Begin Your Transformation Today

Follow the learn-scale-improve workflow on two to three representative repositories, refine your transformation definitions, then scale across your portfolio.
To dive deeper into AWS Transform custom bulk automation capabilities, explore these resources:

      • AWS Transform custom Documentation — Technical documentation covering all capabilities, API references, and integration guides: AWS Transform custom
      • Scaled Execution Sample Repository — Open-source scripts for running transformations across multiple repositories and transformation definitions: aws-transform-custom-samples
      • Transformation Registry — Discover AWS-managed transformations and create custom definitions: aws-transform-custom-samples

Contact your AWS account team or visit the AWS Transform custom documentation to begin your journey.


About the authors

meghan-author

Meghan Kothari

Meghan Kothari is a Senior Technical Product Manager with the Customer Experience and Business Trends team, where he partners with AWS leadership on strategic deep dives to discover evolving trends in agentic AI-driven application development and modernization. His background as a solutions architect and full-stack developer gives him a unique hands-on perspective to help shape the developer experience. 

Venu-author

Venugopalan Vasudevan

Venugopalan Vasudevan (Venu) is a Principal Specialist Solutions Architect at AWS, where he leads Agentic AI initiatives focused on AWS Transform. He helps customers adopt and scale AI-powered developer and modernization solutions to accelerate innovation and business outcomes.

grilli-author

Rodney Grilli

Rodney Grilli is a Principal Technologist at AWS, specializing in product and code modernization using agentic AI services. He builds solutions that help customers modernize their product portfolios and accelerate their transformations into AI-Native Enterprises.

Automating Incident Investigation with AWS DevOps Agent and Salesforce MCP Server

Post Syndicated from Rohit Sharma original https://aws.amazon.com/blogs/devops/automating-incident-investigation-with-aws-devops-agent-and-salesforce-mcp-server/

This post was co-written with Ross Belmont, Senior Director, Rodrigo Duran, Strategist Director at Salesforce

Every minute counts when managing a critical infrastructure incident. Organizations need to quickly identify issues, diagnose root causes, and implement solutions—all while keeping customers informed. AWS DevOps Agent changes this by automating investigation and response, reducing mean time to resolution (MTTR) from hours to minutes.

In this post, you’ll learn how to integrate AWS DevOps Agent with Salesforce Hosted MCP Server to create an autonomous incident investigation workflow. This integration connects customer support cases directly to infrastructure diagnostics, reducing response times, and facilitating consistent incident resolution across your organization.

The Challenge: The Cost of Manual Incident Investigation

Customer complaints like “the website is slow” often trigger hours of investigation across distributed systems, fragmented telemetry, and multiple teams. Your customer support team lacks the deep infrastructure expertise to diagnose root causes, while your DevOps Engineers are constantly interrupted and pulled away from systematic improvements.

This handoff between teams creates friction:

  • Increased mean time to detect (MTTD) – Issues sit in queues waiting for the right expert
  • Extended mean time to resolve (MTTR) – Manual investigation across Amazon CloudWatch, AWS CloudTrail, application logs, and deployment history is time-consuming
  • Context loss – Information gets lost in translation between support tickets and infrastructure analysis
  • Reactive problem solving – Teams spend time on symptoms rather than preventing recurring issues
This diagram illustrates the traditional, manual incident response workflow before AWS DevOps Agent integration. It shows the friction-filled handoff process where a customer reports an issue to the support team, who then manually escalates it to DevOps engineers. The flow highlights pain points including increased mean time to detect (MTTD), extended mean time to resolve (MTTR), context loss between teams, and reactive problem-solving. The visual emphasizes how information gets lost in translation between support tickets and infrastructure analysis, with issues sitting in queues waiting for the right expert.

Figure 1 – Manual Support Process without DevOps Agent

AWS DevOps Agent integrated with Salesforce changes this paradigm by connecting support workflows directly to autonomous infrastructure investigation, eliminating manual handoffs and reducing investigation time.

How It Works – A Seamless Flow from Customer Complaint to Infrastructure Diagnosis

This diagram depicts the streamlined, automated incident response workflow enabled by AWS DevOps Agent integrated with Salesforce. It shows four key steps: case creation in Agentforce Service, autonomous investigation by DevOps Agent across AWS observability services, case enrichment with technical findings posted back to Salesforce, and preventative recommendations. The flow eliminates manual handoffs between support and engineering teams, connecting customer complaints directly to infrastructure diagnostics for faster resolution and consistent incident handling.

Figure 2 – Automated Support Process with DevOps Agent

  1. Case Creation: Your customer reports an issue in Agentforce Service (e.g., “My Load Balancer is showing unavailable”). Salesforce Flow detects the new case and triggers the AWS DevOps Agent via an API or webhook call.
  2. Autonomous Investigation: DevOps Agent starts an investigation and identifies the root cause. The agent queries AWS observability services, third-party platforms like Splunk and Datadog, code repositories, and CI/CD pipelines. It builds a dynamic topology graph to map relationships between application resources.
  3. Case Enrichment: Investigation findings automatically post back to the Salesforce case, providing your support team with technical context and root cause analysis.
  4. Preventative Recommendations: The agent suggests architectural improvements to help prevent recurrence.

Real-World Example: The Single Instance Outage

The Incident

A customer opens a case in Agentforce Service reporting an application as unavailable.

Salesforce Agentforce Service interface displaying a customer-reported support case. The case details include the customer's complaint about an application being unavailable. This is the starting point of the automated investigation workflow, where a customer opens a case reporting a service disruption. The interface shows standard Salesforce case fields such as account information, incident description, and timing details that will be used by AWS DevOps Agent to initiate its autonomous infrastructure investigation.

Figure 3 – Agentforce Service case details

The Investigation

Salesforce Flow triggers DevOps Agent when the case is created:

  1. Case Retrieval: The agent uses the Salesforce soql_query tool to retrieve case details, including the customer’s account, incident description, and timing. The tool is made available via Salesforce Hosted MCP.

    Salesforce soql_query tool, made available via Salesforce Hosted MCP, to retrieve case details from Salesforce. The query pulls information including the customer's account, incident description, and timing. This is the first step of the autonomous investigation, where the agent programmatically accesses Salesforce CRM data to understand the reported issue before beginning infrastructure diagnostics

    Figure 4 – Salesforce SOQL Query

  2. Topology Discovery: The agent maps the infrastructure and identifies all components of the application.
  3. CloudWatch Metrics Analysis: The agent examines metrics during the incident window and discovers the count of requests dropped to zero during the unavailability period.

    CloudWatch metrics analysis, providing additional detail on the request count data during the incident window. Together with Figure 5a, it forms the complete picture of the traffic pattern showing the drop to zero requests. The agent uses this telemetry data as quantitative evidence to support its root cause analysis, correlating the exact timing of the traffic drop with other events discovered during the investigation, such as CloudTrail administrative actions.

    CloudWatch metrics analysis performed by AWS DevOps Agent during the investigation. It displays a request count chart for the affected application during the incident window. The metrics reveal that the count of incoming requests dropped to zero during the unavailability period reported by the customer. This data point is critical evidence the agent uses to correlate the customer complaint with actual infrastructure behavior, confirming that the application was indeed unreachable during the reported timeframe.

    Figure 5 – Request Count Chart

  4. CloudTrail Event Analysis: The agent discovers a sequence of administrative actions that caused the downtime.

    AWS DevOps Agent analyzing CloudTrail events during the incident timeframe. The agent discovers a sequence of administrative actions that caused the application downtime. CloudTrail provides an audit trail of API calls made in the AWS account, and the agent examines these events to identify what infrastructure changes occurred around the time of the outage. This step is crucial for correlating operational events with the observed metrics drop, helping the agent build a timeline of the incident.

    Figure 6 – CloudTrail Analysis

  5. Root Cause Determination: The agent correlates the administrative actions with the metrics drop, identifying that an EC2 instance termination caused the outage.

    AWS DevOps Agent's root cause determination. The agent correlates the administrative actions found in CloudTrail with the CloudWatch metrics drop, identifying that an EC2 instance termination caused the outage. The findings show the specific sequence of events: an EC2 instance was terminated, which caused the application to become unavailable since it was running on a single instance without redundancy. This demonstrates the agent's ability to autonomously connect multiple data sources to pinpoint the exact cause of an incident.

    Figure 7 – Root Cause Details

  6. Case Update: The agent uses the Salesforce create_sobject_record tool to post findings to the case Activity feed. The tool is made available via Salesforce Hosted MCP.

The Result

Your Salesforce case now contains a comprehensive root cause analysis with timeline, affected resources, and contributing factors.

Salesforce Agentforce Service case after AWS DevOps Agent has posted its investigation findings. The case now contains a comprehensive root cause analysis including a timeline of events, affected resources, and contributing factors. The support team can see the technical diagnosis directly within their familiar Salesforce interface without needing to escalate to engineering. This demonstrates the case enrichment step where investigation results flow back to Salesforce automatically via the Hosted MCP Server.

Figure 8 – Agentforce Service case updated with root cause

The Mitigation Plan

The agent generates an actionable mitigation plan showing how to prevent recurrence.

The actionable mitigation plan generated by AWS DevOps Agent after completing its root cause analysis. The plan outlines specific recommendations for preventing recurrence of the incident, such as implementing redundancy and auto-scaling. Rather than just identifying what went wrong, the agent proactively suggests architectural improvements. This transforms incident response from a purely reactive process into an opportunity for systematic infrastructure improvement, helping organizations build more resilient systems over time.

Figure 9 – Mitigation Plan

The agent also provides step-by-step remediation instructions that you can apply immediately. Due to length, this shows a portion of the plan.

Showing a portion of the step-by-step remediation instructions generated by AWS DevOps Agent. These instructions provide specific, immediately actionable guidance that operations teams can follow to implement the recommended mitigations. The instructions go beyond high-level recommendations to include concrete implementation steps. Due to length, only a portion of the full plan is shown, demonstrating the depth and specificity of the agent's remediation guidance for preventing future occurrences of the identified issue.

Figure 10 – Step by Step Mitigation instructions

Technical Implementation

Prerequisites: Before implementing this integration, verify you have:

  1. Agentforce Service with Salesforce Hosted MCP Server enabled
  2. AWS DevOps Agent Space configured in your AWS account
  3. Amazon CloudWatch and AWS CloudTrail enabled for observability
  4. Infrastructure resources tagged for topology mapping (optional)
  5. Familiarity with Salesforce Flow Builder for workflow automation

This integration requires configuration in both Salesforce and AWS. The following steps provide an overview of the setup process.

  1. Create Agent Space: Set up a DevOps Agent Space in your AWS account with appropriate IAM roles and permissions.
  2. Integrate Observability Tools: Connect your operational tools like Splunk, Datadog, or New Relic to provide the agent with telemetry data.
  3. Connect Code Repositories: Link GitHub, GitLab, or AWS CodeCommit to enable the agent to correlate incidents with recent deployments.
  4. Build Topology Mapping: Tag your infrastructure resources, so the agent focuses on components relevant to your application.
  5. Add Skills: Configure the agent with instructions to direct the investigation – for example, to update Agentforce Service cases when investigations are complete.

Highlighted below are the key setup steps:

Create Agent Space

An Agent Space defines the AWS accounts, integrations, and access controls for your DevOps Agent investigations. When you create your Agent Space, configure a skill that instructs the agent to post investigation findings back to Salesforce cases.
AWS DevOps Agent Space configuration interface where an agent skill is being set up for Salesforce integration. The skill provides specific instructions directing the agent to update the originating Agentforce Service case when an investigation completes. This configuration step is part of the technical implementation, defining the agent's workflow behavior. Skills tell the agent what actions to take, in this case posting investigation findings back to the Salesforce case that triggered the investigation.

Figure 11 – Agent Skill for Salesforce

The skill provides specific instructions for the agent’s workflow – in this case, directing it to update the originating Agentforce Service case when the investigation completes.

Salesforce Hosted MCP Server Setup

The Salesforce Hosted MCP Server enables AWS DevOps Agent to query case data and post investigation findings back to Salesforce. Configure the MCP Server in your Salesforce org using the following steps. For complete instructions, see the Salesforce documentation and the Salesforce Hosted MCP GitHub Repository.

Add the Salesforce Hosted MCP Server to Your Agent Space

In the AWS Console, register the Salesforce MCP Server with your Agent Space. This connection allows DevOps Agent to query Salesforce case data and post investigation findings.

After registration, test by manually triggering an investigation from the AWS Console. Instruct the agent to retrieve case details from Salesforce and post the root cause analysis back to the case.
When configuring MCP tools, follow best
security practices.
AWS DevOps agent Operator Console interface for manually triggering a DevOps Agent investigation. It demonstrates how to instruct the agent to retrieve case details from Salesforce and post root cause analysis back to the case. This manual trigger is used during initial setup and testing before automating the workflow with Salesforce Flow. The interface shows the investigation prompt and configuration, including the connection to the Salesforce Hosted MCP Server for bidirectional communication between AWS and Salesforce.

Figure 12 – Starting an Investigation

In the next step, you’ll automate this workflow using Salesforce Flow, so investigations trigger automatically when cases are created.

Using Salesforce Flows

Salesforce Flows automate the connection between case creation and DevOps Agent investigations. Flow is a no-code automation tool that uses a visual drag-and-drop interface (Flow Builder) to automate business processes.

Configure a Flow trigger on your Case object to invoke DevOps Agent automatically when cases are created.

Salesforce Flow trigger configuration on the Case object. The trigger is set to fire automatically when new cases are created, initiating the DevOps Agent investigation workflow without manual intervention. This is the automation component that connects Salesforce case creation to AWS DevOps Agent, replacing the manual process of escalating issues to engineering teams. The Flow Builder's visual interface shows the trigger conditions that determine when the automated investigation should begin.

Figure 13 – Salesforce Trigger

The Flow calls the DevOps Agent webhook with case details including the customer account, incident description, and timing. This triggers an autonomous investigation without requiring manual handoff to engineering teams. Due to length, this shows a portion of the Flow.

Salesforce Flow that automates the connection between case creation and AWS DevOps Agent investigations. The Flow calls the DevOps Agent webhook with case details including customer account, incident description, and timing. Built using Salesforce's no-code Flow Builder with its visual drag-and-drop interface, this automation triggers autonomous infrastructure investigation without requiring manual handoff to engineering teams. Due to length, only a portion of the full Flow is displayed.

Figure 14 – Salesforce Flow

For implementation details and example code, see this Code repository

Connecting Salesforce Flow to AWS DevOps Agent

Configure how Salesforce Flow invokes the DevOps Agent webhook. Choose one of three integration approaches based on your requirements:

  1. Option 1: External Service (Recommended for simplicity)External Service Integrate with AWS services using SigV4 (AWS Signature Version 4) authentication through Named Credentials. This no-code approach is the fastest way to establish the connection.
  2. Option 2: Apex Class (Recommended for custom logic)Create an Apex class that your Flow calls to invoke the webhook. This approach provides flexibility to add custom business logic or error handling before triggering investigations.

Results and Impact

This integration transforms incident response by connecting customer support directly to autonomous infrastructure investigation:

Faster Incident Resolution: Autonomous investigation reduces mean time to resolution (MTTR) by eliminating manual log analysis. The agent detects and diagnoses issues immediately when cases are created, providing 24/7 coverage across time zones.

Reduced Manual Effort: SRE teams focus on systematic improvements instead of responding to individual incidents. Support teams receive technical insights without escalating to engineering, and every investigation follows the same thorough process.

Improved Customer Experience: Customers receive detailed root cause analysis within minutes of reporting an issue. This transparency builds trust, and the agent’s architectural recommendations help prevent recurring problems.

Organizational Learning: Every investigation is documented and searchable, creating a knowledge base of incident patterns. The agent identifies recurring issues across cases and suggests infrastructure improvements to address root causes.

Conclusion

Connecting AWS DevOps Agent with a Salesforce Hosted MCP Server creates an autonomous investigation workflow that eliminates manual handoffs between support and engineering teams. This integration reduces mean time to resolution through instant analysis, improves customer experience with rapid root cause updates, and enables proactive prevention through pattern recognition.

About the Authors

This blog post was authored by:

Conor Manton author photo

Conor Manton

Conor Manton is a Principal Technical Account Manager at AWS, based in San Francisco. He works with strategic enterprise customers to accelerate their cloud journey, with a focus to operationalize AI-powered workflows to drive business outcomes.

Ross Belmont author photo

Ross Belmont

Ross Belmont is a Senior Director of Product Management focused on integrations, with more than 15 years of experience in the Salesforce ecosystem.

Rohit Sharma author photo

Rohit Sharma

Rohit Sharma is a Senior Technical Account Manager at AWS Enterprise Support, based in New York. He partners with strategic enterprise customers to optimize their cloud operations, leveraging AI and automation to reduce operational overhead and improve incident response at scale.

Rodrigo Duran author photo

Rodrigo Duran

Rodrigo Duran is an AI Deployment Strategist Director at Salesforce. Based in São José dos Campos, São Paulo, Brazil. He partners with strategic customers globally to bridge the gap between technical strategy and business impact, scaling AI-powered deployments on the Salesforce platform.

AWS Weekly Roundup: AWS DevOps Agent & Security Agent GA, Product Lifecycle updates, and more (April 6, 2026)

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-aws-devops-agent-security-agent-ga-product-lifecycle-updates-and-more-april-6-2026/

Last week, I visited AWS Hong Kong User Group with my team. Hong Kong has a small but strong community, and their energy and passion are high. They recently started a new AI user group, and we hope more people will join. I was able to strengthen my bond with the community through great food and conversation.

This week, I”ll first take a closer look at some of the key launches.

AWS DevOps Agent and Security Agent GA
At the last re:Invent, we introduced the concept of frontier agents that work autonomously across multiple steps to achieve outcomes, operating continuously until the job is done. The first two—AWS DevOps Agent and AWS Security Agent—are now generally available after the preview.

AWS DevOps Agent helps you run cloud operations—investigating incidents, reducing time to resolution, and preventing issues before they happen. Customers like United Airlines, Western Governors University, and T-Mobile are already using DevOps Agent to accelerate incident response and simplify operations at scale. At WGU, resolution time dropped from hours to minutes, and in preview customers report up to 75% lower MTTR and 3 to 5 times faster resolution. Learn more in Sébastien’s preview blog post and GA announcement.

AWS Security Agent brings continuous, context-aware penetration testing into the development lifecycle. This agent operates like a human penetration tester. Customers including LG CNS, HENNGE, and Wayspring are seeing strong results. At LG CNS, teams estimate over 50% faster testing and ~30% lower costs, along with significantly fewer false positives. Learn more in Esra’s preview blog post and GA announcement.

Both are designed to work across AWS cloud, multicloud, and on-prem environments. You can have an always-available teammate that can handle the heavy lifting, so you can focus on what matters most.

AWS Service Availability Updates
When the availability of an AWS service or feature changes, we provide customers guidance in AWS Product Lifecycle Changes on available alternatives and support for migration so that disruptions to your operations are minimized. The following lifecycle changes were updated on March 31, 2026.

We understand that changes in availability can impact your operations. For specific guidance, consult the relevant service documentation or contact AWS Support.

Last week’s launches
Here are last week’s launches that caught my attention:

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Additional updates
Here are some additional news items that you might find interesting:

For a full list of AWS blog posts, be sure to keep an eye on the AWS Blogs page.

Learn more about AWS, browse and join upcoming AWS led in-person and virtual events, startup events, and developer-focused events as well as AWS Summits and AWS Community Days. Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Channy

Securely connect AWS DevOps Agent to private services in your VPCs

Post Syndicated from Alexandra Huides original https://aws.amazon.com/blogs/devops/securely-connect-aws-devops-agent-to-private-services-in-your-vpcs/

AWS DevOps Agent is your always-available operations teammate that resolves and proactively prevents incidents, optimizes application reliability and performance, and handles on-demand SRE tasks across AWS, multicloud, and on-premises environments. It integrates with your existing observability tools to correlate telemetry, code, and deployment data to reduce Mean Time To Repair (MTTR) and drive operational excellence.

Many organizations extend AWS DevOps Agent with custom Model Context Protocol (MCP) tools and other integrations that give the agent access to internal systems such as private package registries, self-hosted observability platforms, internal documentation APIs, and source control instances like GitHub Enterprise and GitLab. These services often run inside an Amazon Virtual Private Cloud (Amazon VPC) with no public internet access, which means AWS DevOps Agent can’t reach them by default.

Private connections for AWS DevOps Agent let you securely connect your Agent Space to services running in your VPC, or internal network, without exposing them to the public internet. Private connections work with any integration that needs to reach a private endpoint, including MCP servers, self-hosted Grafana or Splunk instances, and source control systems.

In this post, we dive into how private connections work, what makes them secure, and how to set one up using the AWS Management Console and the AWS Command Line Interface (AWS CLI).

How private connections work

A private connection creates a secure network path between AWS DevOps Agent and a target resource in your VPC. Under the hood, AWS DevOps Agent uses Amazon VPC Lattice to establish this secure and private connectivity path. VPC Lattice is an application networking service that lets you connect, secure, and monitor communication between applications across VPCs, accounts, and compute types, without managing the underlying network infrastructure.

When you create a private connection, the following occurs:

  1. You provide the VPC, subnets, and (optionally) security groups that have network connectivity to your target service.
  2. AWS DevOps Agent creates a service-managed resource gateway and provisions its elastic network interfaces (ENIs) in the subnets you specified.
  3. The agent uses the resource gateway to route traffic to your target service’s IP address or DNS name over the private network path.

The resource gateway is fully managed by AWS DevOps Agent and appears as a read-only resource in your account. You don’t need to configure or maintain it. The only resources created in your VPC are ENIs in the subnets you specify. These ENIs serve as the entry point for private traffic and are managed entirely by the service. They don’t accept inbound connections from the internet, and you retain full control over their traffic through your own security groups.

Security

Private connections are designed with multiple layers of security:

  • No public internet exposure: All traffic between AWS DevOps Agent and your target service stays on the AWS network. Your service never needs a public IP address or internet gateway.
  • Service-controlled resource gateway: The service-managed resource gateway is read-only in your account. It can only be used by AWS DevOps Agent, and no other service or principal can route traffic through it. You can verify this in AWS CloudTrail logs, which record all VPC Lattice API calls.
  • Your security groups, your rules: You control outbound traffic from the ENIs through security groups that you own and manage. Traffic from the DevOps Agent is subject to the outbound rules of the security group you associate with the private connection resource gateway ENIs, and the inbound rules of your target.
  • Service-linked roles with least privilege: AWS DevOps Agent uses a service-linked role to manage the resource gateway. This role is scoped to resources tagged with AWSAIDevOpsManaged and cannot access any other resources in your account.
  • DNS support: You can reference your services by their DNS names. Note that the DNS names need to be publicly resolvable.

If you plan on managing your own resource configurations, make sure your organization allows VPC Lattice actions in service control policies (SCPs).

Architecture

The following diagram (figure-1) shows the network path for a private connection:

Figure 1: AWS DevOps Agent private connections

In this architecture:

  1. AWS DevOps Agent initiates a request to your target service.
  2. The request is routed through the service-managed resource gateway.
  3. An ENI in your VPC receives the traffic and forwards it to your target service’s IP address or DNS name.
  4. Your security groups govern which traffic is allowed through the ENIs.
  5. From your target service’s perspective, the request originates from private IP addresses of ENIs within your VPC.

Prerequisites

Before creating a private connection, verify that you have the following:

  • An active Agent Space: You need an existing Agent Space in your account. If you don’t have one, see Getting started with AWS DevOps Agent.
  • A privately reachable target service: Your MCP server, observability platform, or other service must be reachable at a known private IP address or DNS name from the VPC where the resource gateway is deployed. The service can run in the same VPC, a peered VPC, or on-premises, as long as it’s routable from the resource gateway subnets. The service must be listening on a TCP port that you can specify when creating the connection.
  • Subnets in your VPC: Identify one subnet per Availability Zone where the Resource Gateway ENIs will be created. We recommend selecting subnets in multiple Availability Zones for high availability. These subnets must have network connectivity to your target service.
  • (Optional) Security groups: If you want to control traffic with specific rules, prepare up to five security group IDs to attach to the ENIs. If you omit security groups, AWS DevOps Agent uses the VPC default security group.

Private connections are account-level resources. After you create a private connection, you can reuse it across multiple integrations and Agent Spaces that need to reach the same host.

Create a private connection

You can create a private connection using the AWS Management Console or the AWS CLI.

Using the AWS Console

Step 1: Open the AWS DevOps Agent console. In the navigation pane, choose Capability providers:

Figure 2: DevOps Agent Capability Providers

Step 2: Select Private connections.

Figure 3: DevOps Agent private connections

Step 3: Choose Create a new connection.

Figure-4: DevOps agent – Create a new connection

Step 4: Configure the private connection:

For Connection details:

  • Name: Enter a descriptive name for the connection

For Resource location:

  • VPC where your resource is located: Select the VPC where your resource is located, or a VPC that has access to your resource
  • Subnets: One subnet per availability zone in your VPC to host the managed resource gateway ENIs.
  • IP address type: IPv4, IPv6 or dual stack, representing IP address family your private connection should use. I selected dual stack.

Figure-5: DevOps agent – Configure private connection

For Access control:

  • Security groups: Select the security group to be used by DevOps Agent to target your private resources
  • (Optional) TCP port ranges: Optionally restrict the port ranges DevOps Agent can use to connect to your resources. If you don’t specific this, all ports are allowed.

For Service target details:

  • Host address: The DNS name or IP address of your target resource or service. I used mymcpserver.test.skipv5.net. The service IPs must be reachable from the selected VPC. If you choose a DNS name, it must be publicly resolvable.
  • (Optional) Certificate public key: The certificate public key DevOps Agents uses to securely connect to your target.

Figure-6: DevOps agent – Configure private connection (continued)

Select Create Connection.

The connection status changes to Create in progress. This process can take up to 10 minutes. When the status changes to Completed, the network path is ready.

Figure-7: Private connection successfully created

If the status changes to Create failed, verify that the subnets you specified have available IP addresses, that your account has not reached VPC Lattice service quotas, and that no restrictive IAM policies are preventing the service-linked role from creating resources.

Using the AWS CLI

Run the following command to create a private connection. Replace values with your own.

aws devops-agent create-private-connection \
    --name my-test-private-connection \
    --mode '{
        "serviceManaged": {
            "hostAddress": "mymcpserver.test.skipv5.net",
            "resourceGatewayConfig": {
                "create": {
                    "vpcId": "vpc-00ef99bef2632b9ac",
                    "subnetIds": [
                        "subnet-034f636837473de13",
                        "subnet-00bdfb9edf7cc1ca7"
                    ],
                    "securityGroupIds": [
                        "sg-082788aaec0517905"
                    ]
                }
            }
        }
    }'

The response includes the connection name and a status of CREATE_IN_PROGRESS:

{
    "name": " my-test-private-connection",
    "status": "CREATE_IN_PROGRESS",
    "resourceGatewayId": "rgw-0f7415325b107a945",
    "hostAddress": "mymcpserver.test.skipv5.net",
    "vpcId": "vpc-00ef99bef2632b9ac"
}

To check the connection status, use the describe-private-connection command:

aws devops-agent describe-private-connection \
    --name my-test-private-connection

When the status is Completed, your private connection is ready to use.

Verify the connection

After the private connection reaches the Completed state, verify that AWS DevOps Agent can reach your target service:

  1. Open the AWS DevOps Agent console and navigate to your Agent Space.
  2. Start a new chat session.
  3. Invoke a command that uses the integration backed by your private connection. For example, if your MCP tool provides access to an internal knowledge base, ask the agent a question that requires that knowledge base.
  4. Confirm that the agent returns results from the private service.

If the connection fails, verify the following:

  • Security group rules: Verify that the security groups attached to the ENIs allow outbound traffic on the port your service listens on. Also verify that your service’s security group allows inbound traffic from the ENI security group.
  • Subnet connectivity: Verify that the subnets you selected have reachability to your service. If the service runs in a different subnet, confirm that the route tables allow traffic between them.
  • Service availability: Confirm that your service is running and accepting connections on the expected port.

Example: Connect to a self-hosted Grafana instance

One of the most common use cases for private connections is connecting AWS DevOps Agent to a self-hosted Grafana instance. Many teams run Grafana inside a VPC with no public endpoint to visualize metrics, logs, and traces. With the built-in Grafana integration and a private connection, you can give the agent read-only access to your dashboards, alerts, and data sources, the same observability data your on-call engineers rely on during incidents.

AWS DevOps Agent provides a dedicated Grafana integration that hosts the official open-source Grafana MCP server on your behalf, so you don’t need to deploy or manage any MCP server infrastructure yourself. The integration supports Grafana Cloud, Grafana Enterprise, and self-hosted Grafana OSS (v9.1 and later).

For self-hosted instances that aren’t publicly accessible, pair the Grafana integration with a private connection so the agent can reach your instance over the private network.

Step 1: Create a Grafana service account

In your Grafana instance, create a service account with Viewer role permissions. This gives AWS DevOps Agent read-only access to your dashboards, alert rules, and data sources. Generate an access token for the service account and save it for the next step.

Step 2: Create a private connection to your Grafana instance

Because your Grafana instance runs in a private subnet, create a private connection first so that AWS DevOps Agent can reach it.

Using the AWS Console:

Follow the steps in the Create a private connection section of this blog, using your Grafana instance’s address as the host address.

Using the AWS CLI:

aws devops-agent create-private-connection \
    --name grafana-connection \
    --mode '{
        "serviceManaged": {
            "hostAddress": "grafana.internal.example.com",
            "resourceGatewayConfig": {
                "create": {
                    "vpcId": "vpc-0123456789abcdef0",
                    "subnetIds": [
                        "subnet-0123456789abcdef0",
                        "subnet-0123456789abcdef1"
                    ],
                    "portRanges": ["443"]
                }
            }
        }
    }'

Wait for the connection status to reach Completed state before proceeding.

Step 3: Add the Grafana integration to your Agent Space

Register and associate the Grafana service so the agent knows how to connect.

Using the AWS Console:

  1. Open the AWS DevOps Agent console and navigate to your Agent Space.
  2. In the Integrations section, choose Add integration.
  3. Select the Grafana tile.
  4. Enter your Grafana instance URL (for example, https://grafana.internal.example.com).
  5. Paste the service account access token you generated in Step 1.
  6. Choose Save.

Using the AWS CLI:

First, register the Grafana service with your instance URL and service account token:

aws devops-agent register-service \
    --service mcpservergrafana \
    --private-connection-name grafana-connection \
    --service-details '{
        "mcpservergrafana": {
            "name": "grafana",
            "endpoint": "https://grafana.internal.example.com",
            "authorizationConfig": {
                "bearerToken": {
                    "tokenName": "grafana-sa-token",
                    "tokenValue": "<SERVICE_ACCOUNT_TOKEN>"
                }
            }
        }
    }' \
    --region us-east-1

Save the returned serviceId, then associate the Grafana service with your Agent Space:

aws devops-agent associate-service \
    --agent-space-id <AGENT_SPACE_ID> \
    --service-id <SERVICE_ID> \
    --configuration '{
        "mcpservergrafana": {
            "endpoint": "https://grafana.internal.example.com"
        }
    }' \
    --region us-east-1

The response includes webhook information that you can use in Step 4 to configure alert notifications. The agent routes traffic to your Grafana instance through the private connection you created in Step 2, matching on the host address.

To verify the integration, start a chat in your Agent Space and ask the agent something like “Summarize my recent Grafana alerts.” If the agent returns alert data from your dashboards, the private connection and Grafana integration are both working.

Step 4: Enable Grafana webhook notifications (optional)

To let AWS DevOps Agent automatically start investigations when Grafana fires an alert, configure a webhook contact point in your Grafana instance. Point the webhook to your Agent Space’s webhook URL and provide the authentication secret from the integration settings. When an alert triggers, Grafana sends a notification to the agent, which begins an investigation using your Grafana data alongside the other resources in your Agent Space.

For details on the AWS DevOps Agent Grafana integration, and details on how you can also use this integration with AWS Managed Grafana (AMG), check the AWS DevOps Agent Grafana integration documentation.

How DNS resolution and host routing work

When you create a private connection, the host address you provide (for example, my-alb.us-east-1.elb.amazonaws.com) is the DNS name that VPC Lattice resolves to route traffic to your target. This DNS name must be publicly resolvable, even if it resolves to private IP addresses. When you register a service integration and specify an endpoint URL (for example, https://my-grafana.internal.corp), that URL is used for the Host header and Service Name Indicator (SNI) on the TLS connection, it is not used for DNS resolution. This separation means you can point multiple service integrations at the same private connection (and therefore the same target, such as an Application Load Balancer), each with a different endpoint hostname. The target can then use the Host header to route requests to different backends.

For example, you could create a single private connection with your ALB’s DNS name as the host address, and register separate Grafana and MCP server integrations, each with their own endpoint URL. The ALB receives both through the same private connection and uses host-based routing rules to direct each request to the correct target group.

Advanced setup using existing VPC Lattice resources

If your organization already uses Amazon VPC Lattice and manages your own resource configurations, you can create a private connection in self-managed mode. Instead of having AWS DevOps Agent create a resource gateway for you, you provide the Amazon Resource Name (ARN) of an existing resource configuration that points to your target service.

This approach is useful when you:

  • Want full control over the resource gateway and resource configuration lifecycle.
  • Need to share resource configurations across multiple AWS accounts or services.
  • Require VPC Lattice access logs for detailed traffic monitoring.
  • Run a hub-and-spoke network architecture.
  • Require zero trust fine grained access controls for access to your resources or services.

To create a self-managed private connection using the AWS Console, click on Create a new connection, and select Use existing resource configuration, as shown in the following screen capture (figure-8). Then select your existing resource configuration for the drop-down list.

Figure-8: Advanced setting using existing VPC Lattice resources

To create a self-managed private connection with the AWS CLI:

aws devops-agent create-private-connection \
    --name my-advanced-connection \
    --mode '{
        "selfManaged": {
            "resourceConfigurationId": "rcfg-0123456789abcdef0"
        }
    }'

For more details on setting up VPC Lattice resource gateways and resource configurations, see the Amazon VPC Lattice User Guide.

Clean up

To avoid ongoing charges, delete private connections that you no longer need.

Using the AWS Console

  1. Open the AWS DevOps Agent console.
  2. In the navigation pane, choose Capability providers, then choose Private connections.
  3. Select the private connection you want to delete.
  4. Choose Delete.
  5. Confirm the deletion.

Using the AWS CLI

aws devops-agent delete-private-connection \
    --name my-test-private-connection

The response returns a status of DELETE_IN_PROGRESS. AWS DevOps Agent removes the managed resource gateway and ENIs from your VPC. After deletion completes, the connection no longer appears in your list of private connections.

Conclusion

Private connections for AWS DevOps Agent provide a secure, managed way to connect your Agent Space to services running inside your VPC. By using Amazon VPC Lattice, private connections keep all traffic off the public internet while your existing security control remain in place, giving you full control over network access through your own security groups.

To get started, open the AWS DevOps Agent console and create your first private connection. For more details, see Private connections in the AWS DevOps Agent User Guide.

About the authors

Alex Huides

Alexandra Huides

Alexandra Huides is a Principal Networking Specialist Solutions Architect in the AWS Networking Services product team at Amazon Web Services. She focuses on helping customers build and develop networking architectures for highly scalable and resilient AWS environments. Alex is also a public speaker for AWS, and is helping customers adopt IPv6. Outside work, she loves sailing, especially catamarans, traveling, discovering new cultures, running and reading.

Tipu Qureshi

Tipu Qureshi

Tipu Qureshi is a Senior Principal Technologist in AWS Agentic AI, focusing on operational excellence and incident response automation. He works with AWS customers to design resilient, observable cloud applications and autonomous operational systems.

Jordan Merrick

Jordan Merrick

Jordan Merrick is a Senior Software Engineer in AWS Agentic AI, where he works on observability and identity. He builds secure, scalable agentic systems for AWS customers.

Mohak Kohli

Mohak Kohli

Mohak Kohli is a Software Development Engineer at Amazon Web Services. He works across various domains with focus on VPC Lattice and PrivateLink.

Leverage Agentic AI for Autonomous Incident Response with AWS DevOps Agent

Post Syndicated from Janardhan Molumuri original https://aws.amazon.com/blogs/devops/leverage-agentic-ai-for-autonomous-incident-response-with-aws-devops-agent/

Introduction

Teams running distributed workloads face a persistent operational challenge: when something breaks, the information needed to resolve it is scattered across logs, deployment pipelines, configuration histories, and third-party monitoring tools. A Site Reliability Engineer (SRE) responding to a 2 AM page must manually correlate telemetry from multiple sources, trace dependencies across services, and form hypotheses — a process that routinely takes hours. As systems grow in complexity, the need for an AI-powered operational teammate — an SRE agent — has become increasingly clear.

The Do It Yourself (DIY) path and its limits

Teams exploring this space often start by using their favorite AI coding tools to help during an investigation, a thin wrapper over an large language model (LLM). On-call engineers wake up and looks at the incident details, tickets, give coding tools access to logs, monitoring tools and ask it to launch investigation. These approaches can deliver value for straightforward scenarios, but real world application architectures at scale require context across accounts, monitoring systems, and application topology awareness, enforce governance and access controls, and retained learning from past incidents to ensure a comprehensive incident management. As environments scale, the gap between a simple coding tool with limited context and a production-grade operational agentic teammate widens.

A fully managed alternative

AWS DevOps Agent is your always-available operations teammate that resolves and proactively prevents incidents, optimizes application reliability and performance, and handles on-demand SRE tasks across AWS, multicloud, and on-prem environments. DevOps Agent delivers a comprehensive agentic SRE paradigm, shifting teams from reactive firefighting to proactive, AI-driven operational excellence.

But what makes AWS DevOps Agent more powerful than what individual SREs can do with their coding agent? In this post, we walk through a serverless URL shortener application on AWS and demonstrate how DevOps Agent — built on topology intelligence, a three-tier skills hierarchy, cross-account investigation, and continuous learning — delivers capabilities that a simple LLM wrapper cannot replicate, acting as a true operational teammate at scale that reduces Mean Time to Resolution (MTTR) from hours to minutes.

Prerequisites

Before getting started with DevOps Agent, ensure you have:

Application Overview

You are an SRE Engineer at a SaaS company that offers URL shortener service deployed on AWS. The application uses fully serverless architecture, creates short codes, redirects to original URLs, and tracks analytics.

Serverless three-tier architecture for a URL shortener application

Fig 1 – URL Shortener Application

This architecture is straightforward to build but operationally complex to troubleshoot. A latency spike in the Redirect function could stem from DynamoDB throttling, a Lambda cold start regression, an API Gateway configuration change, or a CloudFront cache invalidation — and the signals live in different log groups, metrics namespaces, and trace spans. This is exactly where DevOps Agent demonstrates its value as an autonomous operational teammate.

An Investigation in Action

This workflow demonstrates the DevOps Agent autonomously detecting and diagnosing a production incident in just 4 minutes without human intervention, starting when a CloudWatch alarm triggers due to elevated 5xx errors and systematically testing hypotheses until it identifies DynamoDB write throttling caused by a recent code deployment. The DevOps Agent then autonomously posts a complete root cause analysis with specific mitigation recommendations to Slack, including the problematic commit and suggesting either on-demand capacity or a rollback—all accomplished in under 5 minutes from initial alarm to actionable solution.

Diagram showing the step-by-step flow of a logical investigation process

Fig 2. Logical Investigation workflow

Workflow of the AWS DevOps Agent showing how it moves from detecting an incident to analyzing the root cause and suggesting mitigation steps

Figure 3 – AWS DevOps Agent investigation workflow demonstrating the automated flow from initial incident detection through root cause analysis to actionable mitigation recommendations

Why DevOps Agent is Different

DevOps Agent is not a chat interface layered over a large language model. It is built on Amazon Bedrock AgentCore with dedicated infrastructure for memory, policies, evaluations, and observability. Below, we break down six key capabilities — the 6 Cs — that collectively make DevOps Agent a fully functional nextgen operational teammate.

1. Context

An LLM without operational context is limited to generic suggestions. DevOps Agent solves this through Agent Spaces — isolated logical containers that provide cross-account access to cloud resources, telemetry sources, code repositories, CI/CD pipelines, and ticketing systems. Within each Agent Space, DevOps Agent builds an application resource topology by auto-discovering resources — containers, network components, log groups, alarms, and deployments — and mapping their interconnections across AWS, Azure, and on-prem environments. A learning agent runs in the background, analyzing infrastructure, telemetry, and code to generate an inferred topology at the application and service layer . DevOps Agent maintains deep, AWS-native integrations with services like Amazon Elastic Kubernetes Service (EKS), providing introspection into Kubernetes clusters, pod logs, and cluster events for both public and private environments — capabilities that require privileged access external tools don’t have. DevOps Agent doesn’t just know your resource topology, it knows your telemetry, deployment timeline, and infrastructure and application code. It discovers and knows the relationship between resources, alarms, metrics, and log groups. When it detects a latency spike, it automatically checks GitHub, GitLab, Azure DevOps for recent merges, correlates deployment timestamps with metric anomalies, and determines whether a code change is the probable cause. In the URL shortener example, the agent identifies that a commit adding batch DynamoDB writes was deployed 47 minutes before throttling began — a correlation a human SRE might take 30 minutes to discover manually.

In our URL shortener, DevOps Agent maps the dependency chain from CloudFront through API Gateway to each Lambda function and down to the DynamoDB table. When a latency spike hits the URL Redirect function, the agent traces the relationship graph to determine whether the root cause is DynamoDB read throttling, a Lambda concurrency limit, or an API Gateway timeout configuration — correlating CloudWatch metrics, Lambda traces, and DynamoDB consumed capacity in a single investigation.

2. Control

Context without governance creates risk. Agent Spaces provide centralized control over what the agent can access and how it operates. Administrators define which AWS and Azure accounts, telemetry and code integrations, and MCP servers are available within each Agent Space using granular IAM permissions, This eliminates the inconsistency of individual developers configuring their own toolchains — some thoroughly, some partially, some not at all — and removes the need for ad-hoc onboarding processes for new team members. Every reasoning step and action is logged in immutable audit journals that the agent cannot modify after recording, providing complete transparency into decision-making. AWS DevOps Agent is secured from day one with immutable audit trails logging every reasoning step and tool invocation, AWS CloudTrail integration, IAM Identity Center authentication with granular permissions, and Agent Space-level data governance that isolates investigation data and respects organizational security configurations.

For the URL shortener, the administrator configures a single Agent Space with read access to the production account’s CloudWatch logs, the DynamoDB table metrics, the GitHub repository, and the Slack channel for incident coordination. Every SRE on the team inherits this consistent, controlled configuration — no individual setup required.

3. Convenience

Once an Agent Space is configured, every developer and SRE on the team gets immediate, zero-setup access to the agent’s full operational context — topology, telemetry, code repositories, and ticketing integrations — without configuring anything themselves. This is a meaningful departure from the alternative, where each engineer individually connects their coding agent to Model Context Protocol (MCP) servers for CloudWatch, their observability tool, their source repository, and their ticketing system. In practice, some engineers will complete that setup, some will partially configure it, and some never will — resulting in inconsistent tooling across the team and an onboarding burden for every new hire. With DevOps Agent, the admin configures the Agent Space once, and engineers simply log in to the Operator Web App, or interact through Slack — whichever tool they already use. The agent provides context-aware responses, maintains conversation history, and supports natural language queries against the application topology without any per-user setup.

For the URL shortener team, a new SRE joining the on-call rotation doesn’t need to spend a day wiring up access to the three Lambda function log groups, the DynamoDB metrics dashboard, and the GitHub repository. They log in to the Agent Space and immediately ask, “Show me all Lambda functions connected to this DynamoDB table” — the topology, telemetry access, and code context are already there.

Screenshot showing how the AWS DevOps Agent connects to MCP servers and communication tools

Fig 4 – AWS DevOps Agent MCP server and Communications integrations

Screenshot showing the AWS DevOps Agent's telemetry integration configuration

Fig 5 – AWS DevOps Agent Telemetry integrations

Screenshot showing the AWS DevOps Agent's multi-cloud and pipeline integration settings

Fig 6 – AWS DevOps Agent Multi-Cloud and pipeline integrations

4. Collaboration

DevOps Agent is not a passive Q&A tool, it is an autonomous teammate. When an incident triggers via a CloudWatch alarm, PagerDuty alert, Dynatrace Problem, ServiceNow ticket, or any other event source you configure through the webhook, the agent begins investigating immediately without human prompting. It generates hypotheses, queries telemetry and code data sources to test them, and coordinates across collaboration channels — posting investigation timelines in Slack, updating ServiceNow tickets, and routing findings to stakeholders. Extensibility through the MCP and built-in integrations with CloudWatch, Datadog, Dynatrace, New Relic, Splunk, Grafana, GitHub, GitLab, and Azure DevOps ensures the agent can pull signals from wherever the team’s operational data lives. The agent also performs proactive weekly prevention recommendations, analyzing recent incidents to suggest specific improvements across code optimization, observability coverage, infrastructure resilience, and governance practices. Additionally, DevOps Agent operates within the broader frontier agent ecosystem, where investigation findings can include agent-ready instructions for Kiro to implement fixes.

When the URL shortener experiences a DynamoDB throttling event at 3 AM, DevOps Agent detects the alarm, investigates autonomously, identifies that a traffic spike exceeded the table’s provisioned capacity, and posts a mitigation plan in Slack — all before the on-call engineer finishes reading the page. The weekly prevention evaluation then recommends switching to on-demand capacity mode and adding a CloudWatch alarm on ConsumedWriteCapacityUnits to catch future spikes earlier.

Screenshot showing Slack notifications sent by the AWS DevOps Agent during an investigation

Fig 7 – AWS DevOps Agent Slack investigation notifications

Screenshot showing prevention recommendations generated by the AWS DevOps Agent in the Ops Backlog

Fig 8 – AWS DevOps Agent prevention recommendations in the Ops Backlog

5. Continuous Learning

This is where AWS DevOps Agent most clearly separates itself from thin LLM wrappers. The agent implements a sophisticated three-tier skill hierarchy:

  • AWS-provided skills – Built-in capabilities developed by AWS engineers and scientists that reflect proven operational approaches and are continuously maintained under the hood.
  • User-defined skills – Custom skills that you define to help the agent work more effectively within your specific organizational context and workflows.
  • Learned skills – Operating continuously in the background, AWS DevOps Agent includes a learning sub-agent that performs two critical functions. First, it scans your cloud infrastructure, telemetry data, and code repositories to continuously learn and update your application topology—understanding resources and their relationships to help zero in on key logs related to specific alarms. Second, it analyzes past investigations to identify patterns and optimize future troubleshooting workflows, becoming more effective over time.

For the URL shortener, after DevOps Agent resolves three DynamoDB throttling incidents over a month, the Learning Agent identifies the recurring pattern and generates a learned skill that accelerates future investigations of the same class. The next time throttling occurs, the agent skips exploratory hypotheses and immediately checks provisioned capacity against consumed capacity, reducing investigation time further. The SRE team also uploads a runbook describing their canary deployment process, which the agent references when evaluating whether a recent deployment correlates with an incident.

Screenshot showing user-defined and learned skills configured for the AWS DevOps Agent

Fig 9 – AWS DevOps Agent user-defined and learned skills

6. Cost Effective

You could build your own agent, but you would still need to pay for the model tokens it consumes. More importantly, you would need to staff a team to develop, maintain, and operate the agent and its integrations. You would also need to periodically evaluate model quality, latency, and costs as underlying models change. With AWS DevOps Agent, you get a team of AWS engineers and scientists who do all of that for you.

DevOps Agent uses usage-based pricing — you pay only for the time the agent actively works on a task. There is no per-seat licensing or idle infrastructure cost. The agent works at machine speed, completing investigations in minutes that would take a human engineer hours, and only charges for the actual seconds of active computation.

Behind the scenes, DevOps Agent employs significant data retrieval optimizations that reduce cost while improving accuracy. Its query optimization techniques across tools achieve up to 15x faster querying across massive datasets by leveraging AWS-specific access patterns and data characteristics. These optimizations mean the agent consumes less compute per investigation while delivering more precise results — a direct benefit of deep AWS integration that generic LLM wrappers cannot replicate.

For the URL shortener, instead of an SRE spending two hours manually querying CloudWatch Logs Insights across three Lambda function log groups and correlating with DynamoDB metrics, DevOps Agent completes the same investigation in minutes using optimized queries — at a fraction of the cost of engineering time.

Proven real-world results

Customers and partners using AWS DevOps Agent in preview report up to 75% lower MTTR, 80% faster investigations, and 94% root cause accuracy, enabling 3–5x faster incident resolution.

Western Governor’s University (WGU), a leading online university serving over 191,000 students, was among the first organizations to deploy Amazon DevOps Agent into production, doing so even ahead of the preview launch at re:Invent. As a large-scale Dynatrace user, WGU leverages the DevOps Agent’s native Dynatrace integration, enabling Dynatrace Intelligence to automatically route problem records to the Agent for investigation and return enriched findings directly back into Dynatrace.

During a recent production investigation, WGU’s SRE team used the AWS DevOps Agent to analyze a service disruption scenario, reducing total resolution time from an estimated two hours to just 28 minutes—a 77% improvement in MTTR. AWS DevOps Agent quickly pinpointed the root cause within an AWS Lambda function’s configuration, surfacing critical operational knowledge that had previously existed only in undiscovered internal documentation.

Zenchef is a restaurant technology platform that helps restaurants manage reservations, table operations, digital menus, payments, and guest marketing from a single commission-free system. With a focused DevOps team managing several production environments across multiple business units, they faced a real test when an API integration issue affecting a downstream partner surfaced during a company hackathon, with engineers engaged in the event and nothing significant showing up in monitoring to point them in the right direction.

Rather than pulling engineers off the hackathon, the team brought the issue to AWS DevOps Agent. It worked through the problem systematically, ruling out authentication as a contributing factor, shifting investigation focus on Amazon Elastic Container Service (Amazon ECS) deployments, and ultimately tracing the root cause to a code regression in which a new version failed to handle an unrecognized enum value in the database. The full investigation wrapped in 20-30 minutes, roughly a 75% reduction compared to the 1-2 hours it would have taken manually, and the findings were shared directly with the responsible engineer.

Conclusion

AWS DevOps Agent is architecturally distinct from LLM wrappers. Its topology intelligence service maps AWS service relationships to understand application dependencies. Its three-tier skill hierarchy with a validation-based Learning Agent creates compounding operational knowledge specific to each customer environment. Its cross-account investigation capability, governed autonomy model, and immutable audit trails address enterprise requirements that no external wrapper can satisfy.

The 6 Cs — Context, Control, Convenience, Collaboration, Continuous Learning, and Cost Effective — are not marketing categories. They represent concrete engineering investments: Agent Spaces for isolation, topology, optimized log queries for performance, federated credential management for cross-account access, and a skills architecture that learns and improves with every investigation. For any team operating distributed and complex architectural applications on AWS — DevOps Agent reduces the operational burden of incident response while building institutional knowledge that makes every future investigation faster and more accurate.

Ready to get started? Visit the AWS DevOps Agent documentation to explore the setup process, join the AWS DevOps Agent workshop for hands-on experience, and/or contact your AWS account team to configure your first Agent Space.

Tipu Qureshi

Tipu Qureshi is a Senior Principal Technologist in AWS Agentic AI, focusing on operational excellence and incident response automation. He works with AWS customers to design resilient, observable cloud applications and autonomous operational systems.

Bill Fine

Bill Fine is a Product Management Leader for Agentic AI at AWS, where he leads product strategy and customer engagement for AWS DevOps Agent.

Joe Alioto

Joe is a World Wide Senior Specialist Solutions Architect for Cloud Operations focusing on Observability and Centralized Operations Management on AWS. He has over two decades of hands-on operations engineering and architecture experience. When he isn’t working, he enjoys spending time with his family, learning new technologies and pc gaming.

Janardhan Molumuri

Janardhan Molumuri is a Principal Technical Leader at AWS, comes with over two decades of Engineering leadership experience, advising customers on Cloud and AI Adoption strategies and emerging technologies including generative AI. He has passion for thought leadership, speaking, writing, and enjoys exploring technology trends to solve problems at scale.

AI-powered event response for Amazon EKS

Post Syndicated from Aritra Nag original https://aws.amazon.com/blogs/architecture/ai-powered-event-response-for-amazon-eks/

Cloud environments with dozens of microservices are now easier to manage than ever, and modern DevOps teams are well-equipped to balance rapid deployments with operational stability — even as monitoring tools surface thousands of daily signals.

AWS DevOps Agent is a fully managed autonomous AI Agent that resolves and proactively prevents incidents, continuously improving reliability and performance of applications in AWS, multicloud, and hybrid environments. It brings Kubernetes-native intelligence to incident response. It understands how Pods relate to Deployments, which Services route traffic, what ConfigMaps provide configuration, and how these components interact across your environment. Rather than seeing isolated infrastructure issues, the agent comprehends the architectural relationships that matter most for fast, accurate root cause analysis. In this post, you’ll learn how AWS DevOps Agent integrates with your existing observability stack to provide intelligent, automated responses to system events.

Architecture Diagram of DevOps AgentFigure 1: This is an example of target architecture of how Amazon EKS workloads are deployed and how AWS DevOps agent can interact with the different managed services like Amazon CloudWatch

How AWS DevOps Agent discovers Kubernetes resources

Built on Amazon Bedrock, the agent can analyze complex operational scenarios and correlate data from multiple sources. AWS DevOps Agent combines natural language processing (NLP) of logs and error messages with root cause analysis, powered by machine learning (ML), to automatically identify issues across your infrastructure.

Telemetry-based discovery

The agent analyzes OpenTelemetry data to infer runtime relationships:

  • Service Mesh Analysis: Examines network traffic patterns between pods to identify service-to-service communication
  • Trace Correlation: Uses distributed traces to map request flows across microservices
  • Metric Attribution: Associates performance metrics with specific pods, containers, and nodes

Metadata enrichment

The agent enriches discovered resources with contextual information:

  • Labels and Annotations: Extracts application metadata, ownership information, and deployment details
  • Resource Specifications: Captures CPU/memory requests and limits, health check configurations, and environmental variables
  • Network Topology: Maps pod IPs, service cluster IPs, ingress rules, and network policies

Discovery process

When you start an investigation, the agent executes the following discovery workflow:

  1. Initial Scan: Queries the Kubernetes API for all resources in relevant namespaces
  2. Dependency Analysis: Builds a dependency graph showing how resources relate to each other
  3. Telemetry Correlation: Matches discovered resources with their corresponding metrics, logs, and traces
  4. Context Building: Aggregates resource state, recent events, and performance data into a unified view

Implementation details

Prerequisites

Before implementing this solution, verify that you have the following:

Development environment

As part of the setup and the applications that are mentioned in the following sections. We have this AWS samples repo with deployable scripts and setup instructions.

This section walks you through deploying and configuring the complete AWS DevOps Agent demo environment.

Step 1: Deploy AWS DevOps Agent infrastructure

Begin by deploying the AWS DevOps Agent using the AWS CDK. The infrastructure includes the Agent Space configuration, IAM roles and policies, and integration with your EKS cluster.

Screenshot of the AWS DevOps Agent web interface showing a form to create a new Agent Space named "OTEL-DevOpsAgent-Demo-v1". The form includes fields for agent space name and description, radio button options for configuring IAM roles for AWS resource access and web app access, auto-generated role names, and Cancel and Create action buttons.

Figure 2: This is screenshot of configuring the Agent Space in the AWS Console

Configure the Agent Space in the AWS Console by navigating to the AWS DevOps Agent service. You will then create a new Agent Space for your EKS cluster. Finally, you will set up data source integrations including Prometheus workspace endpoints, Amazon CloudWatch Log groups, and X-Ray service configuration.

Screenshot of the AWS DevOps Agent Capabilities configuration tab for the OTEL-DevOpsAgent-Demo-v1 agent space. The interface displays a Cloud capability section with a primary AWS account (ID: 123456789012) showing a Valid status, a secondary sources section with no entries, and options to add additional source accounts.Figure 3: This is screenshot of validating the connectivity to data sources and access to the AWS account

Validate the deployment by accessing the DevOps Agent web interface, verifying connectivity to data sources, and confirming that the agent can discover your EKS cluster resources.

Screenshot of the AWS DevOps Agent Incident Response Dashboard for the OTEL-DevOpsAgent-Demo-v1 project. The dashboard includes a text area to describe a new investigation, quick-start template buttons for common scenarios (Latest alarm, High CPU usage, Error rate spike), a bar chart showing daily investigation frequency from January 29 to February 4 with one investigation on February 4, and an empty investigations table filtered by Pending Start status.

Figure 4: This is screenshot of checking the incident response and if there is any ongoing investigation

Step 2: Set up port forwarding for applications

Configure port forwarding to enable the traffic generator to access your deployed applications. Set up port forwarding for all sample applications using “kubectl” commands. Each application runs on different ports to simulate a realistic microservices environment:

# Sample Metrics App (port 8000)
kubectl port-forward svc/sample-metrics-app 8000:8000 -n default &
# Python OTEL App (port 8080)
kubectl port-forward svc/otel-sample-app 8080:8000 -n default &
# Go OTEL App (port 8090)
kubectl port-forward svc/go-otel-sample-app 8090:8080 -n default &
# Java OTEL App (port 8081)
kubectl port-forward svc/java-otel-sample-app 8081:8080 -n default &

Step 3: Install and configure Traffic Generator

The traffic generator is a Python-based tool that creates realistic load patterns and error scenarios for testing AWS DevOps Agent capabilities. Install the required Python dependencies and make the traffic generator executable:

# Install required Python packages
pip install requests
# Make the script executable
chmod +x traffic-generator.py

The traffic generator supports multiple configuration options for creating different testing scenarios.

Step 4: Generate baseline traffic

Create baseline operational data by generating normal traffic patterns across all applications. This establishes normal operational patterns that AWS DevOps Agent can learn from. Generate steady traffic to establish baseline metrics:

# Generate normal baseline traffic
python traffic-generator.py --app all --duration 900 --rps 10 --error-rate 0.05

Terminal output showing the initialization of an EKS Platform Traffic Generator script targeting four OTEL applications — Sample Metrics App, Python OTEL App, Go OTEL App, and Java OTEL App — each configured for 900 seconds at 15 requests per second with a 10% error rate. All four services are confirmed available at their respective localhost ports.

This command generates traffic to all applications for 15 minutes at 10 requests per second with a 5% error rate, simulating normal operational conditions. Monitor the baseline traffic generation by checking application metrics and HPA scaling behavior:

# View HPA status (should show scaling based on metrics)
kubectl get hpa -A
# Check custom metrics availability
kubectl get --raw /apis/custom.metrics.k8s.io/v1beta1 | jq .
# View specific metric values
kubectl get --raw /apis/custom.metrics.k8s.io/v1beta1/namespaces/default/pods/*/sample_app_requests_rate | jq .

System log output from a load testing session displaying real-time performance metrics including elapsed time, total requests, success and failure counts, success rate percentage, and requests per second (RPS). The log spans timestamps from 22:38:49 to 22:40:41, showing a consistent RPS of approximately 14.8–14.9 and alternating cycles of 0%, ~90%, and 100% success rates across approximately 9,000 to 10,650 total requests.

Step 5: Configure AWS DevOps Agent Investigation

Set up AWS DevOps Agent to monitor your EKS cluster and prepare for event investigation workflows.

Screenshot of the AWS DevOps Agent Incident Response interface showing the investigation timeline for the "Demo CPU Spike" incident created on 2026-02-04. The timeline displays a user request describing a 97.5% CPU spike on an EKS workload, followed by two assistant responses tracking investigation progress. The investigation was completed at 20:02:40 on the same day.Figure 5: This is screenshot of overall timeline of the ongoing investigation through AWS DevOps agent

Access the AWS DevOps Agent through the AWS Console:

  1. Navigate to AWS DevOps Agent in the AWS Console.
  2. Select your configured Agent Space.
  3. Select Operator access to open the DevOps Agent web application.
  4. Configure data source connections to verify proper integration.

Figure 6: This is screenshot of validating the access to the observability data from the cluster

Verify that the AWS DevOps Agent can access observability data from your cluster including metrics from Amazon Managed Prometheus, logs from Amazon CloudWatch Logs, traces from AWS X-Ray, and topology information from your EKS cluster. DevOps agent can also pull the service map information of your kubernetes resources.

Testing scenarios and use cases

This section demonstrates different testing scenarios that showcase AWS DevOps Agent capabilities in various operational situations.

Scenario 1: Normal load testing

This scenario establishes baseline operational patterns that AWS DevOps Agent can learn from and use for anomaly detection. Generate steady traffic to establish baseline metrics:

python traffic-generator.py --app all --duration 900 --rps 10 --error-rate 0.05

Command-line output report summarizing traffic generation test results for three applications. The Sample Metrics App achieved a 100% success rate across 13,365 requests, while both the Go OTEL App and Java OTEL App recorded 0% success rates with all 13,455 requests failing. The overall success rate was 90.49% at an average of 14.92 requests per second. A green checkmark confirms traffic generation completed for all applications, followed by next steps for monitoring with Prometheus, Grafana, and AWS DevOps Agent.What this test does: The command runs a 15-minute (900-second) steady traffic test across all applications at 10 requests per second, with a 5% simulated error rate. This low, consistent load represents typical production traffic and gives the agent enough signal to establish a reliable operational baseline.
Screenshot of the AWS DevOps Agent Root Cause analysis tab for the "Demo CPU Spike" incident. The investigation, completed on 2026-02-04 at 20:02:40, identifies one key finding: the HorizontalPodAutoscaler (HPA) for the go-otel-sample-app failed to retrieve the custom metric "go_app_requests_rate" from the custom metrics API 472 times between 16:19:44Z and 18:17:43Z, preventing automatic workload scaling during the incident.
Figure 7: This is screenshot of investigation and root cause found in one of the cluster

What you should observe: During this scenario, the AWS DevOps Agent learns normal operational baselines. In the agent’s investigation dashboard, you will see the following being captured and recorded:

Typical request patterns and response times — The agent records average latency and throughput across all services, establishing what “healthy” looks like for your environment.
Normal error rates and distribution — With a 5% error rate, the agent learns the expected noise floor for errors, so it can distinguish genuine incidents from routine fluctuations.
Resource utilization patterns — CPU, memory, and network usage are tracked per pod and node, giving the agent a reference point for what normal resource consumption looks like under standard load.
Service dependency relationships — The agent maps how services communicate with each other, identifying upstream and downstream dependencies that will be critical for root cause analysis in future incidents.

After the test completes, you should see a stable metrics summary in the agent dashboard showing consistent throughput, low error variance, and steady resource utilization — confirming that a reliable baseline has been captured.

Expected outcomes:

During this scenario, the AWS DevOps Agent learns normal operational baselines. These baselines include typical request patterns and response times, normal error rates and distribution, resource utilization patterns, and service dependency relationships.

Scenario 2: Simulated production event

This scenario demonstrates the AWS DevOps Agent’s ability to investigate and analyze events with elevated error rates and performance degradation:

python traffic-generator.py --app java-otel --duration 600 --rps 30 --error-rate 0.25

Figure 8: This is screenshot of details of the Nodes and telemetry data which is relevant for the investigations

What this test does: The command targets the java-otel application specifically, running a 10-minute (600-second) high-load test at 30 requests per second — three times the baseline — with a 25% error rate. This simulates a degraded service experiencing both a traffic surge and a significant increase in failures.

Figure 9: This is screenshot of review and recommended next steps after the analysis of the root cause

What you should observe: Once the test begins, the AWS DevOps Agent detects the deviation from the established baseline and initiates an investigation. In the agent’s incident response view, you will see the following outcomes:

Affected application identification — The agent pinpoints java-otel-app as the impacted service, distinguishing it from other applications running normally in the cluster.
Error pattern analysis — The agent breaks down the 25% error rate into specific failure modes (for example, HTTP 500 errors, timeout spikes, or connection refusals), helping you understand not just that errors are occurring, but why and where.
Resource utilization correlation — The agent correlates CPU and memory spikes on the affected pods with the observed performance degradation, showing a clear relationship between resource exhaustion and increased error rates.
Root cause identification with confidence scoring — The agent presents a ranked list of potential root causes, each with a confidence score, so you can prioritize your investigation. For example, it may identify a memory leak or thread pool exhaustion as the most likely cause with high confidence.

Advanced analysis capabilities: Beyond the immediate incident, the agent performs deeper analysis that you can explore in the investigation timeline view:

Cross-service impact correlation — The agent identifies whether the degradation in java-otel-app has cascading effects on dependent services, showing you the full blast radius of the incident.
Timeline reconstruction — The agent reconstructs the sequence of events leading up to and during the incident, helping you understand how the situation evolved over time.
Dependency mapping — Upstream and downstream service dependencies are visualized, making it clear which services are affected directly and which are at risk.
Prioritized remediation recommendations — The agent provides actionable remediation steps ranked by business impact, so your team can address the most critical issues first. Recommendations may include scaling the affected deployment, adjusting resource limits, or rolling back a recent configuration change.

After the test completes, you should see a full incident report in the agent dashboard summarizing the root cause, affected components, timeline, and recommended next steps — giving your team everything needed to resolve the issue and prevent recurrence.

Expected outcomes:

The agent identifies which application is affected (java-otel-app), analyzes error patterns and rates for specific failure modes, correlates resource utilization with performance degradation, and provides potential root causes with confidence scoring.

Figure 10: This is screenshot of mitigation plan suggested by the AWS DevOps agent

Advanced analysis capabilities:

The agent performs analysis including cross-service impact correlation, timeline reconstruction of event progression, dependency mapping to identify upstream/downstream effects, and prioritized remediation recommendations based on business impact.

AWS DevOps Agent Investigation workflow

This section details how to use AWS DevOps Agent for event investigation and analysis.

Screenshot of the "Start an investigation" modal dialog in the AWS DevOps Agent Incident Response Dashboard. The dialog displays pre-filled investigation details describing an increase in application error rates, an investigation starting point noting an error spike for a workload tagged DemosFor: OTEL-DevOpsAgent-AiforOperations within the last 20 minutes, and an incident timestamp of 2026-02-04T21:30:00. Cancel and Start investigating buttons are shown at the bottom.Figure 11: This is screenshot of starting an investigation from the AWS Console inside AWS DevOps agent service

Starting an investigation

Access the AWS DevOps Agent web interface and initiate a new investigation:

  1. Investigation Trigger: Choose from predefined scenarios like “High CPU usage,” “Error rate spike,” or “Performance degradation”
  2. Time Range Selection: Select the time period when you generated traffic or observed issues.
  3. Scope Definition: Provide the AWS Account ID, AWS Region (us-east-1), and specific cluster or application context.
  4. Data Source Configuration: Make sure all observability data sources are properly connected.

Investigation Process

AWS DevOps Agent follows a systematic investigation methodology:

Data Collection Phase:

Screenshot of the AWS DevOps Agent Incident Response interface showing an active investigation for the "Demo Error Spike" incident created on 2026-02-04 at 22:57:20. The investigation timeline on the left shows sequential updates including a user request, assistant responses, and a planning phase. A chat assistant panel on the right displays a welcome message and an input field for asking questions about the investigation.Figure 12: This is screenshot of investigation timeline done by the AWS DevOps agent

This approach correlates metrics from Amazon Managed Prometheus workspace, and analyzes logs from Amazon CloudWatch Logs for error patterns and anomalies. It also reviews distributed traces from AWS X-Ray for service dependencies, and examines application topology and service relationships to provide comprehensive observability during the migration process.

Analysis phase:

Screenshot of the AWS DevOps Agent Incident Response interface during the "Demo Error Spike" investigation. The investigation timeline shows an Update step and a Fetching data step. An assistant response identifies relevant AWS resources in us-east-1 including the dev-eks-automode EKS cluster, and displays a CloudWatch describe_alarm_history API call targeting the incident window from 2026-02-04T21:00:00Z to 21:57:31Z. A chat assistant panel is visible on the right.Figure 13: This is screenshot of analysis done from the AWS Console inside AWS DevOps agent service

This approach identifies patterns and anomalies using MLalgorithms. It correlates events across multiple data sources for comprehensive understanding, applies statistical analysis to determine the significance of observed changes, and compares current behavior against established baselines for accurate detection and assessment of system behavior.

Root cause identification:

Figure 14: This is screenshot of root cause and investigation summary done from the AWS Console inside AWS DevOps agent service

This approach provides systematic root cause analysis with confidence scoring, identifies contributing factors and potential trigger events, maps event timeline with correlated evidence from multiple sources, and suggests most likely causes based on data correlation and pattern analysis to enable efficient troubleshooting and resolution.

Mitigation strategy:

Figure 15: This is screenshot of mitigation summary recommended by the AWS DevOps agent

This approach recommends immediate mitigation actions to resolve current issues. It also suggests long-term prevention strategies to avoid recurrence, provides runbook-style guidance for event response teams, and integrates with existing DevOps workflows and tools for seamless incident response and improvement.

Key features and benefits

Preventing future incidents

AWS DevOps Agent analyzes patterns across your incident investigations to deliver targeted recommendations that continuously improve your operational posture and prevent future incidents.

Screenshot of the AWS DevOps Agent Prevention tab showing a newly started weekly evaluation run for the OTEL-DevOpsAgent-Demo-v1 project. The evaluation has used 3 minutes of a 15-hour budget. The agent summary states no new recommendations were generated for the past week. A recommendation frequency breakdown shows zero items across all four categories: Code optimization, Observability, Infrastructure, and Governance.Figure 16: This is screenshot of prevention tab in the AWS Console for the AWS DevOps agent

DevOps Agent topology

AWS DevOps Agent Topology automatically discovers and maps your entire infrastructure into an interactive, living blueprint. It reveals not only what resources exist, but how they interconnect, depend on each other, and drive system behavior.

Screenshot of the AWS DevOps Agent Topology graph view for Agent Space 442bc2d6-616a-49dd-b13f-e8a43fab0450, displaying 1,806 total discovered resources. The graph is filtered to show Container resources and visualizes three interconnected sections: a left section with OTEL-DevOpsAgent-Demo-v1 ECS clusters and network components, a middle section with StackSets and multiple standalone resource groups, and a right section with additional standalone resources, connected by relationship lines.Figure 17: This is screenshot of topology of Amazon EKS cluster discovered by AWS DevOps agent

Clean up

To avoid ongoing charges, delete the resources that you created while following this walkthrough.

Remove AWS DevOps Agent resources:

  • Delete investigation data and Agent Space configuration through the AWS Console.
  • Remove IAM roles and policies created specifically for the DevOps Agent.
  • Delete any CloudFormation stacks created during deployment.

Conclusion

As organizations continue to embrace cloud-native architectures and DevOps practices, tools like AWS DevOps Agent will become essential for maintaining competitive advantage in an increasingly complex technological landscape.

Ready to add AI powered observability to your container infrastructure? Visit the AWS documentation to access implementation guides, or reach out to your AWS account team to discuss how this automated migration approach can accelerate your cloud modernization journey, while reducing operational overhead.


About the authors

Building a scalable code modernization solution with AWS Transform custom

Post Syndicated from Dinesh Prabakaran original https://aws.amazon.com/blogs/devops/building-a-scalable-code-modernization-solution-with-aws-transform-custom/

Introduction

Software maintenance and modernization is a critical challenge for enterprises managing hundreds or thousands of repositories. Whether upgrading Java versions, migrating to new AWS SDKs, or modernizing frameworks, the scale of transformation work can be overwhelming. AWS Transform custom uses agentic AI to perform large-scale modernization of software, code, libraries, and frameworks to reduce technical debt. It handles diverse scenarios including language version upgrades, API and service migrations, framework upgrades and migrations, code refactoring, and organization-specific transformations. Through continual learning, the agent improves from every execution and developer feedback, delivering high-quality, repeatable transformations without requiring specialized automation expertise.

Organizations need to run transformations using AWS Transform custom concurrently across their entire code estate to meet aggressive modernization timelines and compliance deadlines. Running it at enterprise scale requires a solution to process repositories in parallel, in a controlled remote cloud environment, manage credentials securely, and provide visibility into transformation progress. Today, we’re introducing an open-source solution that brings production-grade scalability, reliability, and monitoring to AWS Transform custom. This infrastructure enables you to run transformations on thousands of repositories in parallel using AWS Batch and AWS Fargate, with REST API access for programmatic control and comprehensive Amazon CloudWatch monitoring.

Requirements for Enterprise-Scale Code Modernization

AWS Transform custom provides powerful AI-driven code transformation capabilities through its CLI. To effectively scale transformations across enterprise codebases, organizations need:

Scale: Ability to run transformations on 1000+ repositories concurrently rather than one-by-one
Infrastructure: Dedicated compute resources for long-running transformations beyond developers’ laptops
API Access: REST API for programmatic orchestration and seamless integration with CI/CD pipelines
Monitoring: Centralized visibility into transformation progress and status across multiple repositories
Reliability: Automatic retries, secure credential management, and built-in fault tolerance

The Solution: Batch Infrastructure with REST API

This solution provides complete, production-ready infrastructure that addresses these challenges:

Core Capabilities

  • Scalable Batch Processing Run transformations on thousands of repositories in parallel using AWS Batch with Fargate. The default configuration (256 max vCPUs, 2 vCPUs per job) supports up to 128 concurrent jobs, with automatic queuing and resource management. The compute environment scales based on your needs and Fargate service quotas.
  • REST API for Programmatic Access Seven API endpoints provide complete job lifecycle management, enabling you to submit single jobs or bulk batches of thousands in one request. The API offers real-time status tracking and progress monitoring, with Amazon Identity and access Management (IAM) authentication ensuring secure access to transformation operations.
  • Multi-Language Container The solution includes a container supporting Java (8, 11, 17, 21), Python (3.8-3.13), and Node.js (16-24) with all build tools pre-installed, including Maven, Gradle, npm, and yarn. The AWS Transform CLI and AWS CLI v2 are bundled in. The container is fully extensible for custom requirements—you can add your own libraries, languages, or tools by customizing the Dockerfile to meet their specific needs
  • Enterprise-Grade Reliability Automatic IAM credential management eliminates long-lived keys, with credentials auto-refreshing every 45 minutes for jobs up to 12 hours. The system includes automatic retries for transient failures (default: 3 attempts), with configurable timeout and retry settings to match your transformation complexity.
  • Comprehensive Monitoring A CloudWatch dashboard provides job tracking with success and failure rates, trends over time, and API and Lambda health metrics. Real-time log streaming enables you to monitor transformation progress and quickly diagnose issues.

Architecture

The solution uses a serverless architecture built on AWS managed services:

AWS Transform custom Batch solution architecture

Key Components:

  • API Gateway: REST API with IAM authentication
  • Lambda Functions: Job orchestration, status tracking, bulk submission
  • AWS Batch: Job queue and compute environment management
  • Fargate: Serverless container execution (no EC2 to manage)
  • S3: Source code input and transformation results output
  • CloudWatch: Logs, metrics, and operational dashboard

Getting Started

Prerequisites

Before deploying, ensure you have:

  • AWS Account with appropriate IAM permissions (ECR, S3, IAM, Batch, Lambda, API Gateway, CloudWatch)
  • AWS CLI v2 configured with credentials or AWS SSO login
  • Docker installed and running
  • Git for cloning the repository
  • Node.js 18+ and AWS CDK (for CDK deployment)
  • Python3for testing the APIs

Deployment Options

Option 1: CDK Deployment (Recommended)

Step 1: Clone the Repository

git clone https://github.com/aws-samples/aws-transform-custom-samples.git

cd aws-transform-custom-samples/scaled-execution-containers

Step 2: Set Environment Variables

export AWS_ACCOUNT_ID=$(aws sts get-caller-identity --query Account --output text)
export CDK_DEFAULT_ACCOUNT=$AWS_ACCOUNT_ID
export CDK_DEFAULT_REGION=us-east-1

Step 3: Verify prerequisites

This checks that Docker is installed and running, AWS CLI v2 is configured with credentials, Git is available, and your AWS account has the required VPC and public subnets.

cd deployment
chmod +x *.sh
./check-prereqs.sh

Step 4: Set up IAM Permissions (Optional, but recommended)

Generate a least-privilege IAM policy instead of using broad permissions:

./generate-custom-policy.sh

This creates iam-custom-policy.json with minimum permissions scoped to your specific resources.

Create and attach the policy:

aws iam create-policy \
  --policy-name ATXCustomDeploymentPolicy \
  --policy-document file://iam-custom-policy.json
aws iam attach-user-policy \
  --user-name YOUR_USERNAME \
  --policy-arn arn:aws:iam::$(aws sts get-caller-identity --query Account --output text):policy/ATXCustomDeploymentPolicy

Note: If you have administrator access, you can skip this step and proceed directly to deployment.

Step 5: Deploy with CDK (One Command Does Everything!)

cd ../cdk
chmod +x *.sh
./deploy.sh

Time: 20-25 minutes (all resources)

What CDK Does Automatically:

  1. Builds Docker image from Dockerfile
  2. Pushes image to ECR
  3. Creates all AWS resources
  4. Configures everything

What Gets Deployed:

  • ECR repository with Docker image
  • S3 buckets (output, source)
  • IAM roles with least-privilege
  • AWS Batch infrastructure (Fargate)
  • 7 Lambda functions
  • API Gateway REST API
  • CloudWatch logs and dashboard

See cdk/README.md for detailed instructions and configuration options.

Step 6: Get Your API Endpoint

After deployment completes, retrieve the API endpoint URL:

export API_ENDPOINT=$(aws cloudformation describe-stacks \
  --stack-name AtxApiStack \
  --query 'Stacks[0].Outputs[?OutputKey==`ApiEndpoint`].OutputValue' \
  --output text)

echo "API Endpoint: $API_ENDPOINT"

This endpoint is used in all subsequent API calls.

Option 2: Bash Scripts (Alternative)

If you prefer manual control over each deployment step or need to customize individual components, use the bash script deployment. See deployment/README.md for the complete 3-step process with detailed explanations of what each script deploys.

Using the Solution

Single Job Submission

Quick test: Run cd ../test && ./test-apis.sh to validate all API endpoints (MCP, transformations, bulk jobs, campaigns).

Submit a Python version upgrade transformation:

cd ..
python3 utilities/invoke-api.py \
  --endpoint "$API_ENDPOINT" \
  --path "/jobs" \
  --data '{
    "source": "https://github.com/venuvasu/todoapilambda",
    "command": "atx custom def exec -n AWS/python-version-upgrade -p /source/todoapilambda -c noop --configuration \"validationCommands=pytest,additionalPlanContext=The target Python version to upgrade to is Python 3.13. Python 3.13 is already installed at /usr/bin/python3.13\" -x -t"
  }'

This API call triggers a Python version upgrade transformation on the todoapilambda public git repository. The transformation uses the AWS Managed transformation to upgrade from the current Python version to Python 3.13. The configuration parameter specifies additional validation command to be run and plan context to specifies the location of python 3.13 installation in the container and the target version. The -x flag is for non-interactive mode of the transformation , and -t flag is to trust all tools for this transformation.

API returns a job ID for tracking. Job names are auto-generated from the source repository and transformation type.

See api/README.md for complete API documentation with examples for Java, Node.js, and other transformations.

Bulk Job Submission

Transform multiple repositories in a single API call:

python3 utilities/invoke-api.py \
  --endpoint "$API_ENDPOINT" \
  --path "/jobs/batch" \
  --data '{
    "batchName": "codebase-analysis-2025",
    "jobs": [
      {"source": "https://github.com/spring-projects/spring-petclinic", "command": "atx custom def exec -n AWS/early-access-comprehensive-codebase-analysis -p /source/spring-petclinic -x -t"},
      {"source": "https://github.com/venuvasu/todoapilambda", "command": "atx custom def exec -n AWS/early-access-comprehensive-codebase-analysis -p /source/todoapilambda -x -t"},
      {"source": "https://github.com/venuvasu/toapilambdanode16", "command": "atx custom def exec -n AWS/early-access-comprehensive-codebase-analysis -p /source/toapilambdanode16 -x -t"}
    ]
  }'

This API call triggers a deep static analysis of the codebase to generate hierarchical, cross-referenced documentation for three open source repositories in parallel. The transformation uses the AWS Managed transformation to generate behavioral analysis, architectural documentation, and business intelligence extraction to create a comprehensive knowledge base organized for maximum usability and navigation.

The API submits these jobs in a async manner. i.e the API returns a batch id upon submitting these jobs to AWS Batch. Then you can monitor the progress as specified below.

See api/README.md for status checking, MCP configuration, and other API endpoints.

Monitoring Progress

Check batch status:

python3 utilities/invoke-api.py \
  --endpoint "$API_ENDPOINT" \
  --method GET \
  --path "/jobs/batch/BATCH_ID"

Response shows real-time progress:

{
  "status": "RUNNING",
  "progress": 45.5,
  "totalJobs": 1000,
  "statusCounts": {
    "RUNNING": 195,
    "SUCCEEDED": 432,
    "FAILED": 23
  }
}

Viewing Results

After a job completes, the results are stored in your S3 output bucket.

S3 Output Structure:

Results are organized by job name and conversation ID:

s3://atx-custom-output-{account-id}/
└── transformations/
    └── {job-name}/                           # e.g., guava-early-access-comprehensive-codebase-analysis
        └── {timestamp}{conversation-id}/     # e.g., 20251227_051626_8f344f5f
            ├── code/                         # Full source code + transformed changes
            └── logs/                         # Execution logs and artifacts
                └── custom/
                    └── {timestamp}{conversation-id}/
                        └── artifacts/
                            └── validation_summary.md

Validation Summary:

AWS Transform CLI generates a validation summary showing all changes made:

s3://atx-custom-output-{account-id}/transformations/{job-name}/{timestamp}{conversation-id}/logs/custom/{timestamp}{conversation-id}/artifacts/validation_summary.md

This file contains:

  • Summary of all code changes
  • Files modified, added, or deleted
  • Validation results
  • Transformation statistics

Download Results:

# Download all results for a specific job
aws s3 sync s3://atx-custom-output-{account-id}/transformations/{job-name}/{timestamp}{conversation-id}/ ./local-results/

# Download just the validation summary
aws s3 cp s3://atx-custom-output-{account-id}/transformations/{job-name}/{timestamp}{conversation-id}/logs/custom/{timestamp}{conversation-id}/artifacts/validation_summary.md ./

# Download transformed code only
aws s3 sync s3://atx-custom-output-{account-id}/transformations/{job-name}/{timestamp}{conversation-id}/code/ ./transformed-code/

Monitoring and Observability

The solution includes a CloudWatch dashboard with operational metrics:

Job Tracking:

  • Completion rate with hourly trends (completed vs failed)
  • Recent jobs table showing job name, timestamp, last message, and log stream
  • Real-time visibility into job execution

CloudWatch Dashboard screenshot for Job tracking

API and Lambda Health:

  • API Gateway request counts and error rates
  • Lambda invocation metrics per function
  • Performance monitoring (duration by function)

CloudWatch Dashboard screenshot for API and Lambda Health

CloudWatch Logs:

All logs are centralized in CloudWatch Logs (/aws/batch/atx-transform) with real-time streaming.

View logs via AWS CLI:

aws logs tail /aws/batch/atx-transform --follow --region us-east-1

Or use the included utility:

python3 utilities/tail-logs.py JOB_ID --region us-east-1

View in AWS Console: CloudWatch → Log Groups → /aws/batch/atx-transform

Model Context Protocol (MCP) Integration

AWS Transform custom supports Model Context Protocol (MCP) servers to extend the AI agent with additional tools. Configure MCP servers via API:

python3 utilities/invoke-api.py \
  --endpoint "$API_ENDPOINT" \
  --path "/mcp-config" \
  --data '{
    "mcpConfig": {
      "mcpServers": {
        "github": {"command": "npx", "args": ["-y", "@modelcontextprotocol/server-github"]},
        "fetch": {"command": "uvx", "args": ["mcp-server-fetch"]}
      }
    }
  }'

The configuration is stored in S3 and automatically available to all transformations. Test with atx mcp tools to list configured servers.

See api/README.md for status checking, MCP configuration, and other API endpoints.

Customization for Private Repositories

You may need to access private repositories and artifact registries. Extend the base container to add credentials:

To access your private Git repositories or artifact registries during transformations:

Two approaches:

  1. AWS Secrets Manager (RECOMMENDED) – Credentials fetched at runtime, never stored in image
  2. Hardcode in Dockerfile (NOT RECOMMENDED) – For testing only

Steps:

  1. Uncomment placeholders in container/entrypoint.sh (Secrets Manager) or container/Dockerfile (hardcoded)
  2. Redeploy container (see below)

See container/README.md for complete setup instructions, examples, and security best practices.

Redeploying after customization:

If using CDK:

cd cdk && ./deploy.sh

CDK automatically detects Dockerfile changes and rebuilds. If changes aren’t detected, force rebuild:

cd cdk && ./deploy.sh —force

If using bash scripts:

cd deployment
./1-build-and-push.sh --rebuild
./2-deploy-infrastructure.sh

The infrastructure will use your custom container with private repository access. You can also customize the container to add support for additional language versions or entirely new languages based on their specific requirements.

See container/README.md for complete examples.

Note: For automated PR creation and pushing changes back to remote repositories after transformation, you have two options: (1) extend container/entrypoint.sh with git commands using your private credentials (see commented placeholder in the script), or (2) use a custom Transformation definition with MCP configured to connect to GitHub/GitLab for more sophisticated PR workflows.

Campaigns

Central platform teams can create campaigns through the AWS Transform web interface to manage enterprise-wide migration and modernization projects. For instance, to upgrade all repositories from Java 8 to Java 21, teams create a campaign with the Java upgrade transformation definition and target repository list. As developers execute transformations, repositories automatically register with the campaign, enabling you to track progress and monitor across your organization.

Creating a Campaign

  1. Setup Users and Login to AWS Transform web application
  2. Create a Workspace and Create a Job
  3. In the chat, specify the type of the job . For example , “I would like comprehensive code analysis on multiple repos”
  4. Based on your request, AWS Transform will display the list of transformation that matches the criteria, in this case “AWS/early-access-comprehensive-codebase-analysis (Early Access)”
  5. Once you confirm the transformation, AWS Transform will create a campaign and a command to execute for the transformation. You can just copy that command and execute via the API as described below replacing the repo details.
atx custom def exec \
--code-repository-path <path-to-repo> \
--non-interactive \
--trust-all-tools \
--campaign 0d0c7e9f-5cb2-4569-8c81-7878def8e49e \
--repo-name <repo-name> \
--add-repo

Executing the Transformation in a Campaign

python3 utilities/invoke-api.py \
  --endpoint "$API_ENDPOINT" \
  --path "/jobs" \
  --data '{
    "source": "https://github.com/spring-projects/spring-petclinic",
    "command": "atx custom def exec --code-repository-path /source/spring-petclinic --non-interactive --trust-all-tools --campaign 0d0c7e9f-5cb2-4569-8c81-7878def8e49e --repo-name spring-petclinic --add-repo"
  }'

Once this transformation Job is successful, you can view the results and dashboard in Web application as well.

Cleanup

To remove all deployed resources:

CDK Cleanup (Recommended)

cd cdk ./destroy.sh

Bash Scripts Cleanup (Alternate)

cd deployment ./cleanup.sh

This script deletes:

  • AWS Batch resources (compute environment, job queue, job definitions)
  • Lambda functions and API Gateway
  • IAM roles
  • S3 buckets (after emptying)
  • CloudWatch logs and dashboard
  • ECR repository

Conclusion

Enterprise software modernization requires infrastructure that can operate at scale with reliability and observability. This solution provides a production-ready platform for running AWS Transform custom transformations on thousands of repositories concurrently.

By combining AWS Batch’s scalability, Fargate’s serverless compute, and a REST API for programmatic access, you can:

  • Accelerate modernization initiatives
  • Reduce manual effort and human error
  • Gain visibility into transformation progress
  • Integrate with existing DevOps workflows

The code repository is open-source, fully automated, and ready for you to deploy in your AWS account today.

Get started today with AWS Transform custom

About the authors

Profile image for Venugopalan Vasudevan

Venugopalan Vasudevan

Venugopalan Vasudevan (Venu) is a Senior Specialist Solutions Architect at AWS, where he leads Generative AI initiatives focused on Amazon Q Developer, Kiro, and AWS Transform. He helps customers adopt and scale AI-powered developer and modernization solutions to accelerate innovation and business outcomes.

Profile image for Dinesh Balaaji Prabakaran

Dinesh Balaaji Prabakaran

Dinesh is a Enterprise Support Lead at AWS who specializes in supporting Independent Software Vendors (ISVs) on their cloud journey. With expertise in AWS Generative AI Services, he helps customers leverage Amazon Q Developer, Kiro, and AWS Transform to accelerate application development and modernization through AI-powered assistance.

Profile image for Brent Everman

Brent Everman

Brent Everman is a Senior Technical Account Manager with AWS, based out of Pittsburgh. He has over 17 years of experience working with enterprise and startup customers. He is passionate about improving the software development experience and specializes in the AWS Next Generation Developer Experience services.

AWS Transform custom: AI-driven Java modernization to reduce tech debt

Post Syndicated from Dinesh Prabakaran original https://aws.amazon.com/blogs/devops/aws-transform-custom-ai-driven-java-modernization-to-reduce-tech-debt/

In today’s rapidly evolving software landscape, maintaining and modernizing Java applications is a critical challenge for many organizations. As new Java versions are released and best practices evolve, the need for efficient code transformation becomes increasingly important. Organizations today face significant challenges when modernizing their Java applications. Legacy codebases often contain outdated patterns, deprecated APIs, and inefficient implementations that hinder performance and maintainability. Traditional manual refactoring approaches are time-consuming, error-prone, and difficult to scale across large codebases. In addition, as developers spend more time on new development and deployment, the volume of technical debt continues to rise, requiring transformation of legacy code at-scale.

AWS Transform custom addresses these challenges through intelligent automation, providing AWS-managed transformations – standardized transformation packages for common scenarios like Java version upgrades. These transformations enable teams to achieve quick wins through standardized, tested transformation patterns that can be executed at scale, bringing significant time and cost savings to customers. In addition, customers can create custom user defined transformations to address technical debt with code transformations across languages, frameworks, and more.

This post explores how to leverage AWS Transform custom’s out-of-the-box transformation for Java upgrades. By the end of this post, you’ll understand how to use these standardized transformations to modernize your Java applications efficiently while maintaining full control over the transformation process.

Introduction to AWS Transform custom

AWS Transform custom uses agentic AI to automate large-scale code modernization, handling language version upgrades, API migrations, framework updates, and organization-specific transformations. Through continual learning, the agent improves from every execution and developer feedback, delivering high-quality, repeatable transformations without requiring specialized automation expertise.

Prerequisites

Before starting your Java modernization journey with AWS Transform custom, ensure you have the necessary development environment, build tools, and AWS Transform custom command line interface (CLI) installed. For detailed prerequisites and setup instructions, refer to the AWS Transform custom Prerequisites Guide.

Understanding the Modernization Scenario

We’ll demonstrate AWS Transform custom using a Movie Service application – a Spring Boot REST API built on Java 8 with Gradle. This represents a typical enterprise modernization challenge with legacy dependencies, outdated patterns, and technical debt.

Leveraging AWS-Managed Transformations

AWS Transform custom focuses on leveraging AWS-managed transformations designed for common modernization tasks like Java version upgrades.
AWS-managed transformations are pre-built, AWS-vetted transformations for common use cases that are ready to use without any additional setup. These transformations provide immediate value with minimal configuration, making them ideal for standard upgrade scenarios.

Understanding AWS Transform custom CLI Capabilities

AWS Transform custom provides a comprehensive command-line interface that enables both interactive and automated transformation workflows:

atx --version                    # Display ATX version
atx --help                       # Display general help
atx custom def list              # List transformation packages
atx                              # Start interactive conversation

For detailed information on all available commands, refer to the AWS Transform custom command reference.

Screenshot of AWS Transform custom interactive mode.
Figure 1:AWS Transform custom interactive mode

Discovering Available Transformations

Use atx custom def list to view all available transformations, including AWS-managed transformations and custom-defined (user-defined) transformations created by your organization. Key AWS-managed transformations include Java/Python/Node.js version upgrades and AWS SDK migrations.

Screenshot of AWS Transform interface displaying categorized lists of AWS Managed transformations and user-defined custom
transformations.
Figure 2: AWS Transform custom lists available AWS Managed and custom-defined (user-defined) transformations

Applying AWS-Managed Transformations

Before applying any transformations, ensure your project is initialized with Git and that all build and test cases are working correctly with Java 8 (Test cases can be skipped when necessary by using the appropriate build command option and instructions to the agent). For Gradle projects, verify that ./gradlew build executes successfully.

The transformation process follows a structured approach:

  1. Ensure Clean Git State:
git status
git add .
git commit -m "Baseline before Java 21 transformation"
  1. Apply Transformation: You can apply transformations using either interactive or direct command modes. In this blog, we will use the interactive mode to walk through the process step-by-step:

Interactive Mode (used in this blog):

First, create a config.json file with your transformation configuration:

{
  "codeRepositoryPath": "/path/to/your/aws-appconfig-java-sample-gradle",
  "transformationName": "AWS/java-version-upgrade",
  "buildCommand": "./gradlew clean build",
  "validationCommands": "build and validate using \"./gradlew clean build\" after transformation to test with java 21",
  "additionalPlanContext": "This is a Java 8 to 21 transformation of a gradle app , also include all dependency migration as well. Use java path /path/to/your/java-8/bin/java and /path/to/your/java-21/bin/java when building before and after transformation. We are using gradle wrapper gradlew, update it if needed for java 21 upgrade. Check for deprecated methods and dependencies and update them."
}

Update the codeRepositoryPath in your config.json to point to your local project directory and update the Java path in additionalPlanContext to match your Java 8 and 21 installation. For more details about configuration files and their parameters, refer to Using Configuration Files.

Then execute the transformation in interactive mode (used for this blog walkthrough):

For Java version upgrade with Gradle using config.json (Interactive Mode):
atx custom def exec -t --configuration file://config.json

Screenshot of AWS Transform interface displaying categorized lists of AWS Managed transformations and user-defined custom transformations.
Figure 3: AWS Transform custom execute a gradle transformation in interactive mode with transformation configuration supplied from config.json

Direct Command Mode (alternative approach): Use this mode for automated CI/CD pipelines or when you want to execute transformations without interactive prompts.

atx custom def exec -x -t --configuration “file://config.json”

Parameter explanation: –

--configuration: Specifies the configuration file for interactive mode

– -x: Executes the transformation automatically without interactive prompts (direct mode)

– -t: Enables test mode for validation during execution (direct mode)

--configuration: Specifies the configuration file path with file://prefix (direct mode)

ATX Execution Command Executing AWS managed Java version upgrade transformation for Gradle project using ATX CLI

  1. Review Transformation Plan: AWS Transform custom analyzes your project based on the configuration provided in config.json and generates a comprehensive transformation plan. This plan details all proposed changes, including:
  • Java version updates: Migration from Java 8 to Java 21 configurations
  • API migration patterns: Automatic updates for deprecated APIs and modern alternatives
  • Framework modernization: Spring Boot version upgrades and compatibility updates
  • Dependency modifications: Updated library versions compatible with Java 21
  • Build system updates: Gradle configuration and plugin changes for Java 21 compatibility
  • Code pattern improvements: Implementation of modern Java features and best practices

We recommend doing a thorough review of the transformation plan to ensure it encompasses all expected updates. The additionalPlanContext in your config.json helps guide the transformation to include dependency migrations and Gradle wrapper updates. If adjustments are needed, provide feedback through the CLI interface.

Additionally, if you want to customize the transformation to target additional changes, for example upgrading additional legacy dependencies contained in the project, you can provide this as feedback when reviewing the transformation plan. AWS Transform custom incorporates all feedback provided to refine the transformation plan before proceeding.

  1. Apply the Transformation: After confirming the transformation plan meets your requirements, type proceed and press Enter. AWS Transform custom executes the transformation according to the approved plan.

The transformation process automatically:

– Creates a new branch and commits the transformed changes in there

– Updates Gradle configuration for Java 21

– Migrates Java EE to Jakarta EE packages (if applicable)

– Updates framework dependencies for Java 21 compatibility

– Applies all necessary code changes

– Updates test cases and testing frameworks for Java 21 compatibility

– Runs comprehensive validation builds

Results of AWS-Managed Transformations

After applying the Java version upgrade transformation, below changes are observed:

Configuration Updates: – Java version: 1.8 → 21 – Spring Boot version upgrades – Gradle plugin and configuration updates – Dependency version modernization

To validate the changes, switch to Java 21 and run ./gradlew build to ensure the transformation was successful, then test the application functionality.

Figure 4: displaying Updated Gradle Configuration Gradle build.gradle showing updated Java 21 configuration and modernized
dependencies
Figure 4: Updated Gradle Configuration Gradle build.gradle showing updated Java 21 configuration and modernized dependencies

Figure 5: Updated code where legacy pattern of raw types usage is transformed to generics
Figure 6: Second example of updated code where legacy pattern of raw types usage is transformed to generics
Figure 7: Updated dependency from javax.security to java.security and uses CertificateFactory to get X509Certificate
Figure 7: Updated dependency from javax.security to java.security and uses CertificateFactory to get X509Certificate
Figure 8: Updated Test cases from junit 4 to junit5

Beyond AWS-Managed Transformations: Custom-Defined Transformations

While AWS-managed transformations provide excellent coverage for standard Java modernization scenarios, there are cases where the available AWS-managed transformations may not address your specific transformation requirements. In such situations, AWS Transform custom enables users to create and test their own organization specific, custom-defined transformation definitions.

When to Create Custom-Defined Transformations

Custom-defined transformations become necessary when AWS-managed transformations don’t cover your specific needs, such as proprietary frameworks, organization-specific coding standards, or complex multi-step migration scenarios.

Creating Custom-Defined Transformations

AWS Transform custom enables teams to develop custom transformations using transformation rules and configuration files. This allows organizations to define transformation logic specific to their requirements, test on sample code, and share validated transformations across teams.

AWS Transform custom’s interactive mode (atx) is particularly beneficial for creating Custom-defined transformations, enabling conversational interaction to iteratively refine requirements and get real-time feedback. Custom-defined transformations provide flexibility to extend AWS Transform custom’s capabilities when AWS-managed transformations don’t meet specific modernization needs.

Continual Learning and Knowledge Items

AWS Transform custom automatically learns from each transformation execution to improve future results. For Java upgrades specifically, the service captures patterns like successful refactoring strategies, common dependency conflicts, and framework compatibility matrices across Java versions. This knowledge feeds back into future transformations, making them more accurate at predicting successful upgrade paths and reducing manual intervention.

Knowledge items are account-specific and remain within your AWS account boundaries. Users can enable or disable continual learning, providing full control over this preference.

Conclusion

In this blog, we demonstrated how AWS Transform custom enables efficient Java application modernization using AWS managed transformations. Starting with a legacy Movie Service application running Java 8 and Spring Boot 2.x, we successfully transformed it to Java 21 with modern dependencies and patterns.

The step-by-step process showed how to establish a baseline, discover available transformations using atx custom def list, and apply transformations through AWS Transform custom’s CLI. The result was a fully modernized application with updated Java versions, Spring Boot upgrades, and modern Java features like enhanced switch expressions and local variable type inference – all achieved in minutes rather than weeks of manual refactoring.

Beyond Java Modernization

Beyond Java modernization, AWS Transform custom’s transformation capabilities extend to other programming languages and frameworks, making it a versatile solution for comprehensive application portfolio modernization across diverse technology stacks. The agent supports diverse transformation use cases including:

  • Version upgrades for Java, Python, and Node.js
  • Runtime and API migrations (AWS SDK v1→v2, Boto2→Boto3)
  • Framework transitions and upgrades
  • Language translations and architectural changes
  • Organization-specific, custom-defined transformations

Through its define once, transform everywhere approach, AWS Transform custom enables organizations to capture and amplify transformation knowledge by defining transformations once and executing repeatable tasks across the entire organization. This reduces knowledge silos and ensures consistent quality regardless of team or project scope.
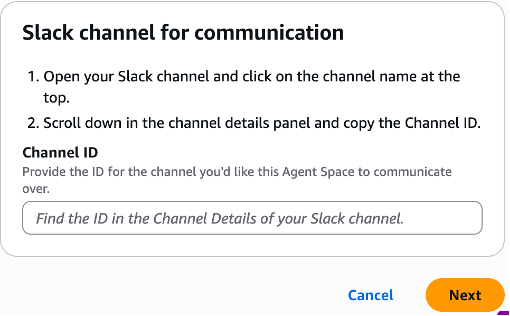
Getting Started

Ready to modernize your Java applications with AWS Transform custom? Here’s how to begin:

  1. Install AWS Transform custom CLI (atx) using the installation script and verify your environment
  2. Configure AWS credentials with transform-custom:* permissions
  3. Explore available AWS-managed transformations using atx custom def list
  4. Apply transformations to your Java applications using direct execution mode (atx custom def exec) or interactive mode (atx)
  5. Validate results through comprehensive testing with ./gradlew build for Gradle projects
  6. Scale across your application portfolio for consistent modernization

Additional Resources

For detailed setup instructions and documentation, visit:

Start your modernization journey today and experience the power of AI-driven code transformation at scale.

About the authors

Profile image for Venugopalan Vasudevan

Venugopalan Vasudevan

Venugopalan Vasudevan (Venu) is a Senior Specialist Solutions Architect at AWS, where he leads Generative AI initiatives focused on Amazon Q Developer, Kiro, and AWS Transform. He helps customers adopt and scale AI-powered developer and modernization solutions to accelerate innovation and business outcomes.

Profile image for Dinesh Balaaji Prabakaran

Dinesh Balaaji Prabakaran

Dinesh is a Enterprise Support Lead at AWS who specializes in supporting Independent Software Vendors (ISVs) on their cloud journey. With expertise in AWS Generative AI Services, he helps customers leverage Amazon Q Developer, Kiro, and AWS Transform to accelerate application development and modernization through AI-powered assistance.

Profile image for Sureshkumar Natarajan

Sureshkumar Natarajan

Sureshkumar Natarajan is a Senior Technical Account Manager at AWS, where he supports Enterprise customers in their cloud journey with a focus on Generative AI initiatives. He guides organizations in leveraging Amazon Q Developer, Kiro, and AWS Transform to unlock new capabilities, streamline development workflows, and achieve transformative business results.

Profile image for Anjan Dave

Anjan Dave

Anjan Dave is a Principal Solutions Architect at AWS with over 25 years of IT experience. He specializes in generative AI application modernization, infrastructure scalability, and developer productivity initiatives.
Anjan leads GenAI and modernization strategies across global projects, influencing technology roadmaps for HCM providers through event-driven and microservices architectures. He advocates for integrating Generative AI into the software development lifecycle to automate routine tasks, enabling engineering teams to focus on high-value architectural work.

Best Practices for Deploying AWS DevOps Agent in Production

Post Syndicated from Greg Eppel original https://aws.amazon.com/blogs/devops/best-practices-for-deploying-aws-devops-agent-in-production/

Root cause analysis during incidents is one of the most time-consuming and stressful parts of operating cloud applications. Engineers must quickly correlate telemetry data across multiple services, review deployment history, and understand complex application dependencies—all while under pressure to restore service. AWS DevOps Agent changes this paradigm by bringing autonomous investigation capabilities to your operations team, reducing mean time to resolution (MTTR) from hours to minutes.

However, the effectiveness of AWS DevOps Agent depends heavily on how you configure your Agent Spaces which control resource access boundaries. An Agent Space that’s too narrow misses critical context during investigations. One that’s too broad introduces performance overhead and complexity. This post provides best practices for setting up Agent Spaces that balance investigation capability with operational efficiency, drawing from our experience onboarding early customers and using DevOps agent across our own teams.

By the end of this post, you’ll understand how to structure Agent Spaces for optimal investigation accuracy, determine the right scope of resource access, and use Infrastructure as Code (IaC) to streamline deployment. Let’s start by understanding the foundational concept that makes all of this possible: the Agent Space itself.

What is an Agent Space and Why Does It Matter?

An Agent Space is a logical container that defines what AWS DevOps Agent can access and investigate. Think of it as the agent’s operational boundary—it determines which cloud accounts the agent can query, which third-party integrations are available, and who can interact with investigations.

Agent Spaces are critical because AWS DevOps Agent needs sufficient context to perform accurate root cause analysis.

When an incident occurs, the agent:

  1. Learns your resources and their relationships across accounts
  2. Correlates telemetry data from logs, metrics, and traces
  3. Reviews recent changes including deployments and configuration updates
  4. Generates and tests hypotheses by querying additional data sources
This view shows the key resources, entities, and relationships DevOps Agent has selected as a foundation for performing it's task efficently.

Figure 1: Agent Space Topology

If the Agent Space doesn’t include access to a critical account or integration, the agent might miss the root cause entirely. Conversely, an overly broad Agent Space introduces performance challenges as the agent considers more resource permutations during investigations.

Understanding these trade-offs between scope and performance is essential. The question becomes: how do you determine the right boundaries for your specific organization and operational model?”

Part 1: Design your Agent Space architecture

We recommend thinking about Agent Space boundaries the same way you think about on-call responsibilities: grant access to accounts relevant to the application, but separate production from non-production environments.

This approach provides several benefits:

  • Familiar mental model – Operations teams already understand on-call boundaries
  • Appropriate investigation scope – Mirrors how human engineers would investigate incidents
  • Two-way door decision – You can expand or narrow Agent Space scope as needs evolve
  • Performance balance – Provides sufficient context without overwhelming the agent

Determine Your Agent Space Boundaries

Start by mapping your application architecture to Agent Space boundaries and consider the following questions:

  • What defines a logical application?
    • Does your team own multiple independent applications? If so, create separate Agent Spaces.
    • Is it a monolith spanning multiple accounts? Then one Agent Space with cross-account access makes sense.
  • How do you organize on-call rotations?
    • Separate teams for production versus non-production suggests separate Agent Spaces.
    • One team handling all environments might work with one Agent Space per application.
  • What are your investigation patterns?
    • Do production incidents require querying dependent services in other accounts? Include those accounts.
    • Are environments completely isolated? Keep Agent Spaces separate.

Example decision tree:

Application: E-commerce Platform
├── Production environment
│ ├── Account 111111111111 (Frontend)
│ ├── Account 222222222222 (API Gateway + Lambda)
│ └── Account 333333333333 (RDS + DynamoDB)
├── Staging environment
│ └── Account 444444444444 (All resources)
└── Development environment
└── Account 555555555555 (All resources)

Recommended Agent Spaces:
→ "EcommerceProd" (accounts 111111111111, 222222222222, 333333333333)
→ "EcommerceNonProd" (accounts 444444444444, 555555555555)

Create one Agent Space per oncall team. The Production Oncall team manages the "EcommerceProd" Agent Space covering production accounts. The Non-Prod Oncall team manages the "EcommerceNonProd" Agent Space covering development and staging accounts. This 1:1 mapping provides operations teams with a familiar mental model where Agent Space boundaries match their existing oncall responsibilities.

Figure 2: Agent Space boundaries mirror on-call team responsibilities

Common Agent Space Patterns and Decision Points

Beyond the basic single-application pattern, organizations encounter more complex scenarios that require careful consideration. Here are critical patterns to address that we’ve seen customers successfully adopt:

Pattern 1: Investigations Spanning Multiple Teams. Large organizations with multiple teams (example: 3 teams managing 100+ production accounts) encounter situations where an issue originates in Team A’s infrastructure but the root cause lies in Team B’s services. The question becomes: how do you enable collaboration across Agent Spaces?

Recommended approach: Create application-specific Agent Spaces that include read-only access to shared resource accounts e.g. dependencies. Establish clear on-call escalation procedures and add them as runbooks when investigations identify cross-team root causes for efficient communication (e.g. via chat in Slack). Configure the shared service team’s resources with tags identifying which applications use them (example: app-id: ecommerce-frontend). Following a consistent tagging strategy provides investigation context for shared resources while maintaining clear resource ownership.

Pattern 2: Shared Services and Network Operations Center (NOC) Teams. Some organizations have centralized teams that provide and support shared infrastructure services (databases, networking, monitoring, security) used by multiple applications across the organization. These NOC or central operations teams need visibility into their services without requiring access to every application’s Agent Space.

Recommended approach: Create a dedicated Agent Space for the shared service team and configure an Agent Space scoped to the shared service team’s infrastructure and operational responsibilities:

  • Include AWS accounts containing shared databases, network infrastructure, centralized logging, and monitoring systems
  • Add relevant CloudFormation stacks for shared platform services
  • Configure IAM roles that provide read-only access to the specific resources the team supports
  • Include runbooks and operational procedures specific to the shared services

This follows the same principle as application-specific Agent Spaces: one Agent Space per on-call team, even when that Agent Space’s scope spans multiple applications. While shared services teams manage specific infrastructure domains, SRE teams often face an even larger challenge: operational responsibility for hundreds or thousands of applications at enterprise scale.

Pattern 3: Central Operations Teams Managing Many Applications. Central operations teams responsible for operational tooling across hundreds or thousands of applications can efficiently manage Agent Spaces at scale using Infrastructure as Code.

Recommended approach: Use the AWS CDK or Terraform samples available as starting points. These samples enable teams to:

  • Define a standardized Agent Space template with your organization’s required IAM roles, integrations, resource boundaries and governance tags
  • Deploy Agent Spaces programmatically as part of application onboarding workflows
  • Enforce compliance through AWS Config rules or service control policies
  • Track all Agent Spaces through consolidated billing and tagging (application-id, team, cost-center, environment)

Central operations teams manage the templates and governance policies, while application teams operate within those guardrails. This approach scales to thousands of applications with consistent configuration and automated deployment. AWS DevOps agent allows limiting agent access in an AWS account and controlling access for users to the operator console for teams to manage Agent Space access at scale.

A small platform team (a few engineers) manages 1,000+ Agent Spaces by maintaining standardized IaC templates (AWS CDK and Terraform). When new applications are registered, a CI/CD pipeline automatically deploys an Agent Space for that application team. This distributed pattern (one Agent Space per app team) scales to many applications without manual intervention, while maintaining investigation accuracy by avoiding a centralized "monitoring account" that would bias toward its primary application.

Figure 3: Enterprise scale pattern using Infrastructure as Code

Now that you understand how to design Agent Space boundaries aligned with your team structure and scale requirements, let’s walk through the practical implementation steps to bring these architectural patterns to life.

Part 2: Implement your Agent Space architecture

This section walks you through the practical steps of creating your first Agent Space—from verifying prerequisites and configuring IAM roles across accounts to integrating observability tools, setting up access controls, and testing your configuration to ensure investigations have the context they need.

Step 1: Agent Space Prerequisites

Before setting up your first Agent Space, ensure you have:

  • AWS accounts – At least one AWS account where your application resources run
  • IAM permissions – Sufficient access to create IAM roles and policies across accounts. AWS DevOps Agent requires two distinct sets of IAM permissions:
    • Agent Space role permissions – The IAM role that AWS DevOps Agent assumes to query your AWS resources, access CloudWatch Logs, and discover topology. This role requires the AIOpsAssistantPolicy managed policy plus additional permissions for AWS Support and expanded capabilities. See the CLI onboarding guide for the complete role configuration.
    • Operator app role permissions – The IAM role that controls what human operators can do in the AWS DevOps Agent web application, such as starting investigations, viewing results, and creating AWS Support cases. This role is separate from the agent’s investigation permissions.
  • Service Control Policies (SCPs) – Verify that your organization’s SCPs allow AWS DevOps Agent API actions. Common issue: Teams complete Agent Space setup but investigations fail because SCPs block aidevops:* actions or bedrock:InvokeModel actions. Review your AWS Organization’s SCPs and add exceptions for DevOps Agent if needed. Note that DevOps Agent and Amazon Bedrock inference are not impacted by policies that restrict customer content to specific AWS regions—Bedrock may use US regions other than US East (N. Virginia) for stateless inference.
  • Observability tools – At minimum, Amazon CloudWatch (automatically available via IAM roles) and Amazon CloudTrail. For comprehensive investigations, integrate Application Performance Monitoring tools like Datadog, Dynatrace, New Relic, Grafana, or Splunk. See Connecting telemetry sources for supported integrations.
  • Understanding third-party integration configuration – Some third-party tools require a two-step configuration process:
    • Account-level registration – Tools that use OAuth (like GitHub, Dynatrace) must first be registered at the AWS account level through the DevOps Agent console. This establishes OAuth credentials that are shared across all Agent Spaces in your account.
    • Agent Space-level association – After registration, each Agent Space individually specifies which resources from that tool to use. For example, after registering GitHub once, Agent Space “EcommerceProd” can associate only production repositories while Agent Space “EcommerceNonProd” associates development repositories.Other tools like Datadog, New Relic, and Splunk can be directly associated with an Agent Space using API keys or tokens without separate account-level registration. CloudWatch requires no additional configuration beyond IAM roles.
  • Source control – GitHub or GitLab repository access for code context and deployment correlation (optional but highly recommended)
  • IaC tooling – AWS CDK (TypeScript/Python), Terraform, AWS CLI, or AWS Management Console for Agent Space deployment

With prerequisites verified, you’re ready to create your Agent Space and establish the IAM trust relationships that enable investigations.

Step 2: Create an Agent Space

AWS DevOps Agent requires IAM roles in each AWS account within the Agent Space boundary. The agent assumes these roles to query CloudWatch Logs, describe resources, and build application topology.

The AWS DevOps Agent is designed to retrieve operational data from multiple AWS Regions across all AWS accounts that you grant access to within the configured Agent Space, enabling comprehensive visibility into distributed infrastructure and applications regardless of their geographic deployment, while supporting multiple accounts through a configuration process that involves creating IAM roles with appropriate trust policies and permissions in secondary accounts

Option A: Use the AWS Console wizard
Navigate to the AWS DevOps Agent console and choose Create Agent Space and follow the guided setup to create IAM roles in each target account.

The Create an Agent Space setup wizard in the AWS Management Console showing Agent Space Details.

Figure 4: Creating an Agent Space in the Console

The setup wizard helps in configuring cross-account trust relationships.

Shows the Agent Space Management Console and in particular the capability to configure your Agent Space to access multiple accounts.

Figure 5: Multiple account configuration for your Agent Space

Option B: Use Infrastructure as Code (Recommended)
We provide sample CDK and Terraform templates that automate Agent Space creation and IAM role deployment across multiple accounts.

AWS CDK example (TypeScript):

//If you have many accounts, use a loop:

const accounts = [
  { id: '111111111111', name: 'Prod', role: prodRole, stage: 'prod' },
  { id: '222222222222', name: 'Dev', role: devRole, stage: 'dev' },
  { id: '333333333333', name: 'Test', role: testRole, stage: 'test' },
];

accounts.forEach(account => {
  const association = new devopsagent.CfnAssociation(this, `${account.name}Association`, {
    agentSpaceId: agentSpace.ref,
    serviceId: 'aws',
    configuration: {
      aws: {
        assumableRoleArn: account.role.roleArn,
        accountId: account.id,
        accountType: 'monitor'
      }
    }
  });

  association.addDependency(agentSpace);
  cdk.Tags.of(association).add('stage', account.stage);
});

For detailed instructions on setting up IAM roles and permissions across accounts, see the CLI Onboarding Guide.

Once your Agent Space exists and has access to AWS accounts, the next critical step is connecting the observability and development tools that provide investigation context beyond AWS native services.

Step 3: Configure Integrations

AWS DevOps Agent investigates incidents by correlating data from multiple sources. The more context available, the more accurate the root cause analysis.

Recommended integrations by priority:

  1. Amazon CloudWatch – Provides logs, metrics, and traces from AWS services. The agent queries CloudWatch Logs Insights automatically during investigations. No additional configuration is needed if IAM roles are properly configured.
  2. Application Performance Monitoring tools – Datadog, Dynatrace, New Relic, and Splunk provide distributed tracing, custom metrics, and application-level context. Configure via Agent Space integrations in the AWS Console.
  3. Code repositories – GitHub or GitLab integration enables the agent to review recent deployments and code changes. Requires OAuth or personal access token.
  4. CI/CD pipelines – GitHub Actions or GitLab workflows help the agent correlate incidents with deployment timing. Configured alongside code repository integration.
  5. Communication Channels – Slack and ServiceNow integration enables DevOps Agent to post real-time investigation updates to team channels and automatically update incident tickets with findings, root cause analysis, and recommended mitigation steps throughout the investigation lifecycle.

Advanced Integrations

Beyond built-in integrations, AWS DevOps Agent supports webhook triggered investigations and custom MCP (Model Context Protocol) servers so you can bring-your-own observability tools.

Webhook configuration for investigation triggers
Webhooks allow external systems (Grafana, Prometheus, PagerDuty, custom monitoring tools) to automatically trigger DevOps Agent investigations when incidents occur. Each Agent Space receives a unique webhook URL that accepts JSON payloads describing the incident.

Common configuration pitfalls:

  • Webhook authentication: Webhooks use HMAC signatures for security. Store the webhook secret in AWS Secrets Manager and rotate it according to your security policies.
  • Payload format: Ensure your monitoring tool sends incident context including timestamps, affected resources, and symptom descriptions. Richer context enables more accurate investigations.

For detailed webhook setup, see Invoking DevOps Agent through Webhook.

Bring-your-own MCP servers
If you use observability tools beyond the built-in integrations (Grafana, Prometheus, custom telemetry systems), you can connect them via MCP servers. MCP servers expose your tool’s data through a standardized protocol that DevOps Agent queries during investigations.

Key requirements for MCP servers:

  • Publicly accessible HTTPS endpoint: MCP servers must be reachable from the public internet. VPC-hosted servers are not currently supported.
  • Read-only tools only: For security, only expose MCP tools that perform read operations. Write operations introduce prompt injection risks.
  • Tool allowlisting: Register MCP servers at the account level, then selectively enable specific tools per Agent Space. Don’t grant access to all tools—choose only those relevant to investigations.

Common MCP setup errors:

  • Authentication misconfiguration: MCP servers support OAuth 2.0 or API key authentication. Verify your OAuth client credentials are correct and that token exchange URLs are accessible from AWS infrastructure.
  • Tool name length: MCP tool names have a maximum length of 64 characters. Longer names will fail registration.
  • Endpoint URL format: Use the full HTTPS URL including path. Example: https://mcp.example.com/v1/mcp not just mcp.example.com.

For comprehensive MCP server setup including authentication configuration, see Connecting MCP Servers.

Testing your integrations
After configuring webhooks or MCP servers, trigger a test investigation to verify connectivity:

  • For webhooks: Send a test payload from your monitoring tool and verify the investigation starts in the DevOps Agent web app
  • For MCP servers: Start an investigation manually and check the agent journal to confirm it successfully called your MCP tools
  • Review any errors in AWS CloudTrail logs which capture all DevOps Agent API calls including integration attempts

With your data sources connected, you now need to ensure the right people have appropriate access to investigations while maintaining security boundaries.

Step 4: Configure Access Controls

Agent Spaces support fine-grained access controls to ensure only authorized team members can interact with investigations.

Access control considerations:

  • Who should view investigations? Typically on-call engineers, SREs, and DevOps engineers. Consider including security teams for security-related incidents.
  • Who should create AWS Support cases? Typically on-call leads and senior engineers. Restrict this permission to prevent excessive case creation.
  • Who should modify Agent Space configuration? Typically central operations or infrastructure teams. Separate this from day-to-day investigation access.

IAM-based access control:

AWS DevOps Agent uses IAM policies to control access to Agent Spaces. Attach policies to IAM users, groups, or roles:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": [
        "devopsagent:GetAgentSpace",
        "devopsagent:StartInvestigation",
        "devopsagent:GetInvestigation",
        "devopsagent:ListInvestigations"
      ],
      "Resource": "arn:aws:devopsagent:us-east-1:123456789012:agentspace/EcommerceProd"
    }
  ]
}

AWS DevOps Agent operates within your AWS environment with privileged access to operational data across multiple accounts. While general security foundations apply, Agent Space configuration introduces specific considerations. For comprehensive security guidance, see the AWS DevOps Agent Security documentation.

Access controls are in place—now it’s time to validate that your Agent Space configuration provides the investigation coverage you need.

Step 5: Test and Iterate

Agent Space configuration is a two-way door decision. Start with a focused scope and expand based on investigation results.

Testing your Agent Space: 

Trigger a test investigation using the AWS DevOps Agent web app.

  • Start an investigation and provide symptoms such as “High latency on /api/checkout endpoint”.
  • Observe which resources the agent queries.
  • Review investigation completeness. Did the agent identify the root cause?
  • Were any accounts or services missing from the investigation?
  • Did the agent have sufficient telemetry data?

Adjust Agent Space boundaries based on results.

  • Add accounts if investigations lack context.
  • Add integrations if telemetry gaps exist.
  • Narrow scope if performance degrades.

Conclusion

AWS DevOps Agent transforms incident response from a manual, time-consuming process into an autonomous, data-driven investigation. However, the agent’s effectiveness depends on proper Agent Space configuration. By following the on-call based approach—granting access to accounts relevant to your application while separating production from non-production environments—you provide sufficient context for accurate root cause analysis without introducing unnecessary complexity.

Key takeaways:

  • Think on-call boundaries – Agent Space scope should mirror how your team investigates incidents
  • Use Infrastructure as Code – CDK and Terraform templates ensure consistent, repeatable deployments
  • Integrate observability tools – More data sources equals more accurate investigations
  • Iterate based on results – Expand or narrow Agent Space scope as investigation patterns emerge

Next steps:

We’re committed to making AWS DevOps Agent easier to adopt and more accurate in solving customer problems. Your
Agent Space setup is the foundation for achieving fast, reliable incident resolution. Have questions or feedback? Leave a comment below.

Authors

Tipu Qureshi

Tipu Qureshi is a Senior Principal Technologist in AWS Agentic AI, focusing on operational excellence and incident response automation. He works with AWS customers to design resilient, observable cloud applications and autonomous operational systems.

Bill Fine

Bill Fine is a Product Management Leader for Agentic AI at AWS, where he leads product strategy and customer engagement for AWS DevOps Agent.

Greg Eppel

Greg Eppel is a Principal Specialist for DevOps Agent and has spent the last several years focused on Cloud Operations and helping AWS customers on their cloud journey.

From AI agent prototype to product: Lessons from building AWS DevOps Agent

Post Syndicated from Efe Karakus original https://aws.amazon.com/blogs/devops/from-ai-agent-prototype-to-product-lessons-from-building-aws-devops-agent/

At re:Invent 2025, Matt Garman announced AWS DevOps Agent, a frontier agent that resolves and proactively prevents incidents, continuously improving reliability and performance. As a member of the DevOps Agent team, we’ve focused heavily on making sure that the “incident response” capability of the DevOps Agent generates useful findings and observations. In particular, we’ve been working on making root cause analysis for native AWS applications accurate and performant. Under the hood, DevOps Agent has a multi-agent architecture where a lead agent acts as an incident commander: it understands the symptom, creates an investigation plan, and delegates individual tasks to specialized sub-agents when those tasks benefit from context compression. A sub-agent executes its task with a pristine context window and reports compressed results back to the lead agent. For example, when examining high-volume log records, a sub-agent filters through the noise to surface only relevant messages to the lead agent.
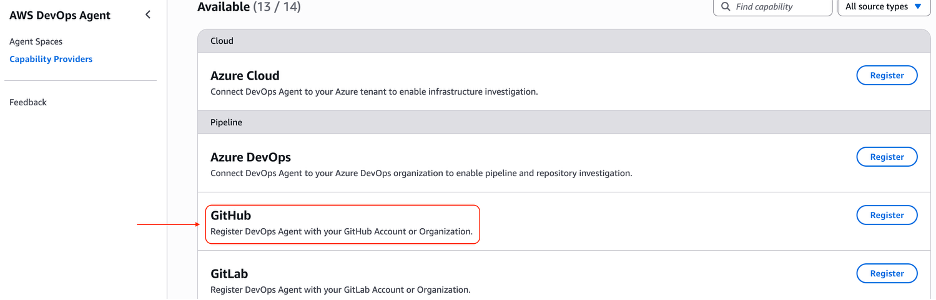
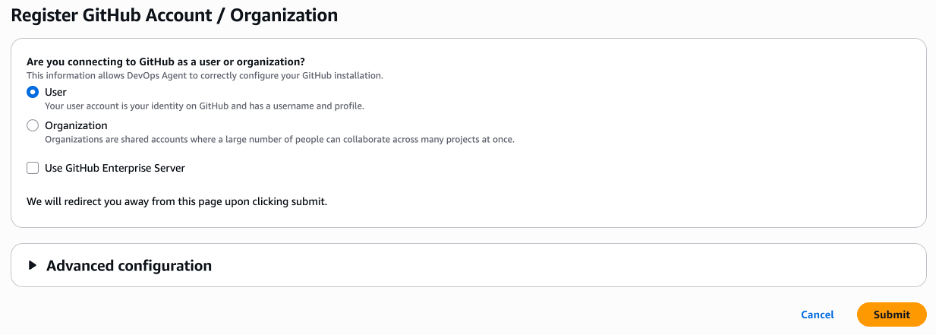
In this blog post, we want to focus on the mechanisms one needs to develop to build an agentic product that works. Building a prototype with large language models (LLMs) has a low barrier to entry – you can showcase something that works fairly quickly. However, graduating that prototype into a product that performs reliably across diverse customer environments is a different challenge entirely, and one that is frequently underestimated. This post shares what we learned building AWS DevOps Agent so you can apply these lessons to your own agent development.

In our experience, there are five mechanisms necessary to continuously improve agent quality and bridge the gap from prototype to production. First, you need evaluations (evals) to identify where your agent fails and where it can improve, while establishing a quality baseline for the types of scenarios your agent handles well. Second, you need a visualization tool to debug agent trajectories and understand where exactly the agent went wrong. Third, you need a fast feedback loop with the ability to rerun those failing scenarios locally to iterate. Fourth, you need to make intentional changes: establishing success criteria before modifying your system to avoid confirmation bias. Finally, you need to read production samples regularly to understand actual customer experience and discover new scenarios your evals don’t yet cover.

Evaluations

Evals are the machine learning equivalent of a test suite in traditional software engineering. Just like building any other software product, a collection of good test cases builds confidence in quality. Iterating on agent quality is similar to test-driven development (TDD): you have an eval scenario that the agent fails (the test is red), you make changes until the agent passes (the test is green). A passing eval means the agent arrived at an accurate, useful output through correct reasoning.

For AWS DevOps Agent, the size of an individual eval scenario is similar to an end-to-end test in the traditional software engineering testing pyramid. Looking through the lens of “Given-When-Then” style tests:

  • Given – The test setup portion tends to be the most time-consuming to author. For the AWS DevOps Agent, an example eval scenario includes an application running on Amazon Elastic Kubernetes Service composed of several microservices fronted by Application Load Balancers, reading and writing from data stores such as Amazon Relational Database Service databases and Amazon Simple Storage Service buckets, with AWS Lambda functions doing data transformations. We inject a fault by deploying a code change that accidentally removes a key AWS Identity and Access Management (IAM) permission to write to S3 deep in the dependency chain.
  • When – Once the fault is injected, an alarm fires, and this triggers the AWS DevOps Agent to start its investigation. The eval framework polls the records that the Agent generates, just like how the DevOps Agent web application renders them. This section isn’t fundamentally different from defining the action in an integration or end-to-end test.
  • Then – This asserts and reports on multiple metrics. Fundamentally, there’s a single “PASS” (1) or “FAIL” (0) metric for quality. For the DevOps Agent’s incident response capability, a “PASS” means the right root cause surfaced to the customer – in our example, this means identifying the faulty deployment as the root cause and tracing the dependency chain to surface the impacted resources and observations that reveal the missing S3 write permission; otherwise “FAIL”. We define this as a rubric: not just “did the agent find the root cause?” but “did the agent arrive at the root cause through the correct reasoning with the right supporting evidence?”The ground truth (the “expected” or “wanted” in software testing parlance) is compared to the system response (the “actual”) via an LLM Judge – an LLM that receives both the ground truth and the agent’s actual output, then emits its reasoning and a verdict on whether they match. We use an LLM for comparison because the agent’s output is non-deterministic: the agent follows an overall output format but generates the actual text freely, so each run may use different words or sentence structures while conveying the same semantic meaning. We don’t want to strictly search for keywords in the final root cause analysis report but rather evaluate whether the essence of the rubric is met.

The evaluation report is structured with scenarios as rows and metrics as columns. Key metrics that we keep track of are capability (pass@k – whether the agent passed at least once in k attempts), reliability (pass^k – how many times the agent passed across k attempts, e.g., 0.33 means passed 1 out of 3 times for k=3), latency, and token usage.

Evaluation results table with two scenario rows. Headers: Scenario, Pass@3, Pass^3, Avg. E2E Latency, Avg. Time-To-First-Observation, and Avg. Total tokens. Lambda throttle scenario shows Pass@3 of 1 and Pass^3 of 1 (highlighted green). SQS permission removal scenario shows Pass@3 of 1 and Pass^3 of 0.33 (highlighted red), indicating it passed only 1 of 3 attempts.

Why are evals important?

There are several benefits to having evals:

  • Red scenarios provide obvious investigation points for the agent development team to increase product quality.
  • Over time, green scenarios act as regression tests, notifying us when changes to the system degrade the existing customer experience.
  • Once pass rates are green, we can improve customer experience along additional metrics. For example, reducing end-to-end latency and/or optimizing cost (proxied by token usage) while maintaining the quality bar.

What makes evals challenging?

Fast feedback loops help developers know whether code works (is it correct, performant, secure) and whether ideas are good (do they improve key business metrics). This may seem obvious, but far too often, teams and organizations tolerate slow feedback loops […] — Nicole Forsgren and Abi Noda, Frictionless: 7 Steps to Remove Barriers, Unlock Value, and Outpace Your Competition in the AI Era

There are several challenges with evals. In decreasing order of difficulty:

  1. Realistic and diverse scenarios are hard to author. Coming up with realistic applications and fault scenarios is difficult. Authoring high fidelity microservice applications and faults is significant work that requires prior industry experience. What we’ve found effective: we author a few “environments” (based on real application architectures) but create many failure scenarios on top of them. The environment is the expensive portion of the evaluation setup, so we maximize reuse across multiple scenarios.
  2. Slow feedback loops. If the “Given” takes 20 minutes to deploy for an eval scenario and then the “When” takes another 10-20 minutes for complex investigations to complete, agent developers won’t thoroughly test their changes. Instead, they’ll be satisfied with a single passing eval, then release to production, potentially introducing regressions until the comprehensive eval report is generated. Additionally, slow feedback loops encourages batching multiple changes together rather than small incremental experiments, making it harder to understand which change actually moved the needle. We’ve found three mechanisms effective for speeding up feedback loops:
    1. Long-running environments for eval scenarios. The application and its healthy state are created once and kept running. Fault injection happens periodically (e.g., over weekends), and developers point their agent credentials at the faulty environment, completely skipping the “Given” portion of the test.
    2. Isolated testing of only the agent surface area that matters. In our multi-agent system, developers can trigger a specific sub-agent directly with a prompt from a past eval run rather than running the entire end-to-end flow. Additionally, we built a “fork” feature: developers can initialize any agent with the conversation history from a failing run up to a specific checkpoint message, then iterate only on the remaining trajectory. Both of these approaches significantly lowers the wait time of the “When” portion.
    3. Local development of the agentic system. If developers must merge changes and release to a cloud environment before testing, the loop is too slow. Running locally enables rapid iteration.

Visualize trajectories

When an agent fails an eval or a production run, where do you start investigating? The most productive method is error analysis. Visualize the agent’s complete trajectory, every user-assistant message exchange including sub-agent trajectories, and annotate each step as “PASS” or “FAIL” with notes on what went wrong. This process is tedious but effective.

For AWS DevOps Agent, agent trajectories map to OpenTelemetry traces and you can use tools like Jaeger to visualize them. Software development kits like Strands provide tracing integration with minimal setup.

Jaeger UI showing a distributed trace for strands-agents with trace ID 941e3b7. The trace spans 25 minutes 17 seconds with 454 total spans across 7 depth levels. The left panel shows a hierarchical tree of service operations including execute_event_loop_cycle, chat, and execute_tool calls for current_time, write_scratchpad, and use_aws. The right panel displays a timeline visualization with horizontal bars representing span durations. The bottom detail panel shows metadata for a selected execute_tool use_aws span, including tags, process information, and logs with gen_ai event data.

Figure 1 – A sample trace from AWS DevOps Agent.

Each span contains user-assistant message pairs. We annotate each span’s quality in a table such as the following:

Error analysis table showing Step 3 with Span ID f182abb7c94a4713. The Description column shows Title: GetQueryResults(Surveying logs) with a JSON content snippet. Duration is T seconds. The Verdict column shows FAIL highlighted in red. The Reasoning column recommends removing @ptr fields, noting the retrieved logs are X tokens and removing @ptr fields from CloudWatch log records can reduce token usage by half.

This low-level analysis consistently surfaces multiple improvements, not just one. For a single failing eval, one will typically identify many concrete changes spanning accuracy, performance, and cost.

Intentional changes

I had learned from my dad the importance of intentionality — knowing what it is you’re trying to do, and making sure everything you do is in service of that goal. — Will Guidara, Unreasonable Hospitality: The Remarkable Power of Giving People More Than They Expect

You’ve identified failing scenarios and diagnosed the issues through trajectory analysis. Now it’s time to modify the system.

The biggest fallacy we’ve observed at this stage: confirmation bias leading to overfitting. Given the eval challenges mentioned earlier (slow feedback loops and the impracticality of comprehensive test suites) developers typically test only the few specific failing scenarios locally until they pass. One modifies the context (system prompt, tool specifications, tool implementations, etc.) until one or two scenarios pass, without considering broader impact. When changes don’t follow context engineering best practices, they likely have negative effects that we can’t capture through limited evals.

You need both diligence and judgment: establish success criteria through available evals and reusable past production scenarios, but also educate yourself on context engineering best practices to guide your changes. We’ve found Anthropic’s prompting best practices and engineering blog, Drew Breunig’s how long contexts fail, and lessons from building Manus particularly helpful resources.

Establish success criteria first

Before making any change, define what success looks like:

  • Baseline. Fix specific git commit IDs for the current system. Think deliberately about which metrics would improve both the agent’s experience and the customer’s experience, then gather those metrics for the baseline.
  • Test scenarios. Which evals will measure your change’s impact? How many times will you rerun these evals? Convince yourself this set represents broader customer patterns, not just the one failure you’re investigating.
  • Comparison. Measure your changes against the baseline using the same metrics.

This intentional framing protects against confirmation bias (interpreting results favorably) and sunk cost fallacy (accepting changes simply because you invested time). If your modifications don’t move the metrics as expected, reject them.

For example, when optimizing a sub-agent within AWS DevOps Agent, we establish a baseline by fixing git commit IDs and running the same scenario seven times. This reveals both typical performance and variance.

Baseline metrics table comparing multiple runs of a sub-agent. Headers: Run, Correct observations, Irrelevant observations, Latency, Sub-agent Tokens, and Lead-agent Tokens. Run 1 shows 4 out of 6 correct observations with 1 irrelevant observation. Run 7 shows 5 out of 6 correct observations with 0 irrelevant observations, demonstrating variance across repeated runs of the same scenario.

Each metric measures a different dimension:

  • Correct observations – How many relevant signals (log records, metric data, code snippets, etc.) that are directly related to the incident did the sub-agent surface?
  • Irrelevant observations – How much noise did the sub-agent introduce to the lead agent? This counts signals that are unrelated to the incident and could distract the agent’s investigation.
  • Latency – How long did the sub-agent take (measured in minutes and seconds)?
  • Sub-agent tokens – How many tokens did the sub-agent to accomplish its task? This serves as a proxy for the cost of running the sub-agent.
  • Lead-agent tokens – How much of the lead agent’s context window is the sub-agent’s input and output consuming? This gives us a tangible way to identify optimization opportunities for the sub-agent tool: can we compress the instructions to the sub-agent or the results it returns?

After establishing the baseline, we compare these metrics against the same measurements with our proposed changes. This makes it clear whether the change is an actual improvement.

Read production samples

We’ve been fortunate to have several Amazon teams adopt AWS DevOps Agent early. A DevOps agent team member on rotation regularly samples real production runs using our trajectory visualization tool (similar to the OpenTelemetry-based visualization discussed earlier, but customized to render DevOps Agent-specific artifacts like root cause analysis reports and observations), marking whether the agent’s output was accurate and identifying failure points. Production samples are irreplaceable; they reveal the actual customer experience. Additionally, reviewing samples continuously refines your intuition of what the agent is good and bad at. When production runs aren’t satisfactory, you have real-world scenarios to iterate against: modify your agent locally, then rerun it against the same production environment until the desired outcome is reached. Establishing rapport with a few critical early adopter teams willing to partner in this way is invaluable. They provide ground truth for rapid iteration and create opportunities to identify new eval scenarios. This tight feedback loop with production data works in conjunction with eval-driven development to form a comprehensive test suite.

Closing thoughts

Building an agent prototype that demonstrates the feasibility of solving a real business problem is an exciting first step. The harder work is graduating that prototype into a product that performs reliably across diverse customer environments and tasks. In this post, we’ve shared five mechanisms that form the foundation for systematically improving agent quality: evals with realistic and diverse scenarios, fast feedback loops, trajectory visualization, intentional changes, and production sampling.

If you’re building an agentic application, start building your eval suite today. Even starting with a handful critical scenarios will establish the quality baseline needed to measure and improve systematically. To see how AWS DevOps Agent applies these principles to incident response, check out our getting started guide.

Efe Karakus

Efe Karakus is a Sr. Software Engineer on the AWS DevOps Agent team, primarily focusing on agent development.

Resolve and prevent operational incidents with AWS DevOps Agent and New Relic

Post Syndicated from Nava Ajay Kanth Kota original https://aws.amazon.com/blogs/devops/resolve-and-prevent-operational-incidents-with-aws-devops-agent-and-new-relic/

This post was co-written with Muthuvelan Swaminathan (Principal Partner Engineer) and Ruchika Bakolia (Software Engineer) from New Relic.

Modern distributed systems that generate massive volumes of metrics, traces, and logs are inherently complex. The process of correlating logs, comparing configurations and switching between tools during incident management makes manual root cause analysis a bottleneck that dramatically increases the mean time to detect and resolve. Instead of manually sifting through mountains of data, Site Reliability Engineers (SREs) and DevOps teams can leverage Agentic AI to automate and enhance the incident resolution process.

To address these challenges, New Relic partnered with AWS to integrate the New Relic Model Context Protocol (MCP) server with AWS DevOps Agent to access telemetry data providing automated root cause analysis and recommendations with cutting-edge artificial intelligence. AWS DevOps Agent is a frontier agent that resolves and proactively prevents incidents, continuously improving reliability and performance of applications in AWS, multi-cloud, and hybrid environments.

In this blog, we’ll explore the key features of both services, how to configure them and an example that shows how operation teams can correlate telemetry data, predict system anomalies and initiate remediation actions to significantly accelerate MTTR (Mean Time to Resolution).

New Relic AI MCP Server

The New Relic MCP Server is a standardized gateway that connects external AI agents such as AWS DevOps Agent to New Relic’s observability data and functions. It enables autonomous agents to query live data and execute actions without requiring custom API integrations.

As customers and partners build their own AI tools, there is no longer a need to maintain a bespoke API integration. MCP enables AI agents to seamlessly interact with their telemetry data on New Relic platform through an MCP client to leverage its capabilities and enhance their workflows.

AWS DevOps Agent

AWS DevOps Agent is a frontier agent that resolves and proactively prevents incidents, continuously improving reliability and performance. AWS DevOps Agent investigates incidents and identifies operational improvements as an experienced DevOps engineer would: by learning your resources and their relationships, working with your observability tools, runbooks, code repositories, and CI/CD pipelines, and correlating telemetry, code, and deployment data across all of them to understand the relationships between your application resources.

Key benefits for organizations 

The integration of in-depth observability with AWS DevOps Agent capabilities is designed to quickly resolve issues when they arise and prevent incidents for SRE and DevOps engineers. Here are few benefits:

  • Automated investigations: AWS DevOps Agent integrates with ticketing and alarming systems like ServiceNow to automatically launch investigations from incident tickets, accelerating incident response within your existing workflows to reduce meant time to resolution (MTTR).
  • Incident coordination: You can also initiate and guide investigations using interactive chat. AWS DevOps Agent acts as a member of your operations team, working directly within your collaboration tools like ServiceNow and Slack to share findings and coordinate responses. 
  • Root cause analysis: AWS DevOps Agent integrates with observability tools, code repositories, and CI/CD pipelines to correlate and analyze telemetry, code, and deployment data, sharing its explored hypotheses, observations, Through systematic investigations, AWS DevOps Agent identifies root cause of issues stemming from system changes, input anomalies, resource limits, component failures, and dependency issues across your entire environment.
  • Detailed mitigation plans: Once AWS DevOps Agent has identified the root cause, it provides detailed mitigations plans, which include actions to resolve the incident, validate success, and revert a change if needed. AWS DevOps Agent also provides agent-ready instructions that can be implemented by another frontier agent, for example, code improvements that can be implemented by Kiro autonomous agent.
  • Proactively future incidents: AWS DevOps Agent analyzes patterns across historical incidents to provide actionable recommendations that strengthen four key areas: observability, infrastructure optimization, deployment pipeline enhancement, and application resilience.

Onboarding

The onboarding process involves setting up an Agent Space and registering your existing New Relic servers. Onboarding does not require any new implementation.

Here are the high-level steps to create an AWS DevOps Agent Space and connect it to the New Relic MCP Server using an API-Key.

Setup Agent Space in AWS DevOps Agent

To create Agent Spaces, navigate to the AWS DevOps Agent page within the AWS Management Console. An Agent Space establishes the boundaries for the AWS DevOps Agent when accessing resources within a specific AWS account. To get started, click the create Agent Space button at the top right of the screen and enter the name, description and IAM roles.

Screen shot displaying orange Create Agent Space button in the AWS Console

AWS DevOps Agent creating agent space

Creating a New Relic association

 Navigate to the capabilities tab in the Agent Space

Screen shot with a red square around the tab for Capabilities in the AWS DevOps Agent -> AgentSpaces view in the AWS Console” width=”1430″ height=”849″></p>
<p style=Navigating to the capabilities tab in the Agent space

Go to the Telemetry section, select Add, then choose New Relic and click Next.

Screen shot with Add a new source radio button selected and Select source to add has radio button New Relic selected

Associating New Relic as the Telemetry provider in the Agent space

Upon successful registration of New Relic as a source, AWS DevOps Agent automatically generates a webhook URL. This URL is then used to receive alert notifications and trigger automated investigations.

Screen shot for Configure Webhook Connection displaying the Webhook URL and Webhook Secret, both are redacted by a black bar.

AWS DevOps Agent Webhook URL and Bearer secret key

The AWS DevOps Agent webhook requires a Bearer token to be included in the HTTP header for authentication purposes. This ensures that only authorized requests are processed. In New Relic, set up Amazon EventBridge as the alert destination. This configuration will trigger an AWS Lambda function that adds the Bearer token to the HTTP header and posts the alert payload to the AWS DevOps Agent webhook URL.

Use Case Walkthrough: Retail Chain – High Latency in shopping cart service resolution

This use case demonstrates how the integration of AWS DevOps Agent and New Relic MCP server empowers SRE and DevOps teams to access the untapped insights in your data to reduce MTTR and drive operational excellence.

Consider the following scenario: AWS DevOps Agent gets paged when the online boutique retail store application cart is experiencing P95 latency > 500ms for more than 2 minutes. This latency spike is critical and far exceeds the normal 5ms threshold, impacting the ability for customers to make purchases. In a typical scenario, the operations team would spend the first 15-30 minutes manually checking dependent services, alerts dashboard, and logs. This manual effort can be significantly reduced by configuring the New Relic observability platform with AWS DevOps Agent to automatically correlate telemetry data and surface the root cause faster.

To automatically remediate this issue, the online boutique application’s microservices are configured with New Relic’s APM agents that collect relevant metrics and send them to New Relic. When the latency exceeds a predefined threshold, an alert condition is triggered within New Relic. The triggered alert sends a notification to EventBridge, which in turn executes the Lambda function. The Lambda transforms the incoming payload into the required AWS DevOps Agent payload template. It then generates an HMAC signature to verify the message’s integrity and authenticity before dispatching it to the AWS DevOps Agent webhook endpoint.

Screen shot displaying new relic logo in the top left corner. The screen is divided into a navigation bar on the left, with Alerts selected. In the pane to the right, Alerts / Alerts Policies is displayed at the top, and below that a title Online Boutique High Latency appears. The notifications tab below that is selected.

Alert policy notifications in New Relic

The AWS DevOps Agent webhook triggers the agent to begin an automated investigation.

Screen shot displaying AWS DevOps Agent / GoldenPath_App in the title bar with Incident Response tab selected. Below that a heading is displayed for Online Boutique All Alerts followed by a timeline displaying User Request then Assistant Response

AWS DevOps Agent Incident response page

The New Relic MCP is first queried by the AWS DevOps Agent to retrieve telemetry data for the cart service GUID. Following this, the AWS DevOps Agent makes a second request to the New Relic MCP to formulate an investigation plan, which includes a list of related entities, their key metrics, and any associated change events for those dependencies.

Zoomed in screen shot of the previous screen with red boxes highlighting two areas in the timeline which say NewRelic MCP list related entities and NewRelic MCP list change events. Each shots the detail for the tool call.

AWS DevOps Agent and New Relic MCP interaction to list entities and related change events

Next, data gathering tasks are executed using New Relic MCP, following the investigation plan.
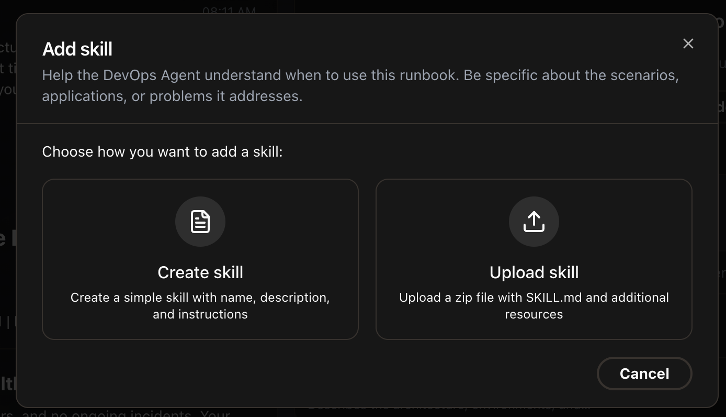
Time line screen similar to the previous screen shot with a red box around the timeline entry for Explore traces.
AWS DevOps Agent and New Relic MCP interaction to explore and analyze traces

Time line screen similar to the previous screen shot with a red box around the timeline entries for NewRelic MCP analyze entity logs and NewRelic MCP analyze golden metrics

AWS DevOps Agent and New Relic MCP interaction to explore and analyze logs and metrics

Continuing its analysis, the agent leverages New Relic’s MCP to examine entity logs, golden metrics, and traces, ultimately identifying the root cause for the latency spike.

Screen shot displaying AWS DevOps Agent / GoldenPath_App in the title bar with Incident Response tab selected. Below that a heading is displayed for Online Boutique All Alerts followed by a timeline displaying Update, Finding, and then Root cause. Root cause has a red box outlining it to draw attention.

AWS DevOps Agent Root Cause Analysis

You can review AWS DevOps Agent’s findings and the suggested root cause. The Site Reliability Engineer (SRE) can interact with the AWS DevOps Agent (side panel) in the chat panel to gain clarification on the steps of the ongoing investigation, enabling more effective monitoring and troubleshooting.

creen shot displaying AWS DevOps Agent / GoldenPath_App in the title bar with Incident Response tab selected. A timeline is visible on the lift and a chat window has been expanded on the right. The chat window contains a question and response.

AWS DevOps Agent Chat interface

You can review AWS DevOps Agent’s findings and the suggested root cause. If necessary, the SRE then executes the appropriate mitigation plan.

Conclusion

By integrating the New Relic MCP server with AWS DevOps Agent, organizations can quickly resolve issues when they arise and proactively prevent future incidents. This collaboration reduces Mean Time to Resolution (MTTR) and accelerates SREs and DevOps teams beyond manual, time-consuming investigations. It ensures rapid remediation of technical disruptions to minimize impact to the business. Ultimately, AWS DevOps Agent, the new frontier agent drives operational excellence, working in conjunction with the New Relic One Observability platform.

About New Relic
The New Relic Intelligent Observability Platform helps businesses eliminate interruptions in digital experiences. New Relic is an AI-strengthened platform that unifies and pairs telemetry data to provide clarity over your entire digital estate for proactive and predictive problem solving. That’s why businesses around the world run on New Relic to drive innovation, improve reliability, and deliver exceptional customer experiences to fuel growth.

Authors

Muthuvelan Swaminathan

Muthuvelan Swaminathan is a Principal Partner Architect at New Relic partnership organization building technical integrations with leading cloud providers and strategic partners. Through partner enablement, solution engineering and ecosystem alignment Muthuvelan helps drive product innovation at New Relic to ensure enterprises eliminate disruptions in their digital experiences for their customers.

Ruchika Bakolia

Ruchika Bakolia is a Software Engineer at New Relic. She is passionate about the intersection of AI and Cloud technologies, with extensive experience building and integrating solutions primarily on AWS. Ruchika enjoys traveling, reading, and exploring creative pursuits like pottery, always seeking out new experiences and challenges.

Nava Ajay Kanth Kota

Ajay Kota is a Senior Partner Solutions Architect at AWS, currently serving on the Amazon Partner Organization (APO) team collaborating closely with ISV Partners. With over 23 years of experience in enterprise computing infrastructure, Ajay brings deep expertise in cloud architecture, storage, backup, and cloud solutions. Before joining AWS, he led Storage, Backup, and Cloud teams, where he was responsible for developing Managed Services offerings across these domains.