Tag Archives: Intermediate (200)

Transforming transactions: Streamlining PCI compliance using AWS serverless architecture

Post Syndicated from Abdul Javid original https://aws.amazon.com/blogs/security/transforming-transactions-streamlining-pci-compliance-using-aws-serverless-architecture/

Compliance with the Payment Card Industry Data Security Standard (PCI DSS) is critical for organizations that handle cardholder data. Achieving and maintaining PCI DSS compliance can be a complex and challenging endeavor. Serverless technology has transformed application development, offering agility, performance, cost, and security.

In this blog post, we examine the benefits of using AWS serverless services and highlight how you can use them to help align with your PCI DSS compliance responsibilities. You can remove additional undifferentiated compliance heavy lifting by building modern applications with abstracted AWS services. We review an example payment application and workflow that uses AWS serverless services and showcases the potential reduction in effort and responsibility that a serverless architecture could provide to help align with your compliance requirements. We present the review through the lens of a merchant that has an ecommerce website and include key topics such as access control, data encryption, monitoring, and auditing—all within the context of the example payment application. We don’t discuss additional service provider requirements from the PCI DSS in this post.

This example will help you navigate the intricate landscape of PCI DSS compliance. This can help you focus on building robust and secure payment solutions without getting lost in the complexities of compliance. This can also help reduce your compliance burden and empower you to develop your own secure, scalable applications. Join us in this journey as we explore how AWS serverless services can help you meet your PCI DSS compliance objectives.

Disclaimer

This document is provided for the purposes of information only; it is not legal advice, and should not be relied on as legal advice. Customers are responsible for making their own independent assessment of the information in this document. This document: (a) is for informational purposes only, (b) represents current AWS product offerings and practices, which are subject to change without notice, and (c) does not create any commitments or assurances from AWS and its affiliates, suppliers or licensors. AWS products or services are provided “as is” without warranties, representations, or conditions of any kind, whether express or implied. The responsibilities and liabilities of AWS to its customers are controlled by AWS agreements, and this document is not part of, nor does it modify, any agreement between AWS and its customers.

AWS encourages its customers to obtain appropriate advice on their implementation of privacy and data protection environments, and more generally, applicable laws and other obligations relevant to their business.

PCI DSS v4.0 and serverless

In April 2022, the Payment Card Industry Security Standards Council (PCI SSC) updated the security payment standard to “address emerging threats and technologies and enable innovative methods to combat new threats.” Two of the high-level goals of these updates are enhancing validation methods and procedures and promoting security as a continuous process. Adopting serverless architectures can help meet some of the new and updated requirements in version 4.0, such as enhanced software and encryption inventories. If a customer has access to change a configuration, it’s the customer’s responsibility to verify that the configuration meets PCI DSS requirements. There are more than 20 PCI DSS requirements applicable to Amazon Elastic Compute Cloud (Amazon EC2). To fulfill these requirements, customer organizations must implement controls such as file integrity monitoring, operating system level access management, system logging, and asset inventories. Using AWS abstracted services in this scenario can remove undifferentiated heavy lifting from your environment. With abstracted AWS services, because there is no operating system to manage, AWS becomes responsible for maintaining consistent time settings for an abstracted service to meet Requirement 10.6. This will also shift your compliance focus more towards your application code and data.

This makes more of your PCI DSS responsibility addressable through the AWS PCI DSS Attestation of Compliance (AOC) and Responsibility Summary. This attestation package is available to AWS customers through AWS Artifact.

Reduction in compliance burden

You can use three common architectural patterns within AWS to design payment applications and meet PCI DSS requirements: infrastructure, containerized, and abstracted. We look into EC2 instance-based architecture (infrastructure or containerized patterns) and modernized architectures using serverless services (abstracted patterns). While both approaches can help align with PCI DSS requirements, there are notable differences in how they handle certain elements. EC2 instances provide more control and flexibility over the underlying infrastructure and operating system, assisting you in customizing security measures based on your organization’s operational and security requirements. However, this also means that you bear more responsibility for configuring and maintaining security controls applicable to the operating systems, such as network security controls, patching, file integrity monitoring, and vulnerability scanning.

On the other hand, serverless architectures similar to the preceding example can reduce much of the infrastructure management requirements. This can relieve you, the application owner or cloud service consumer, of the burden of configuring and securing those underlying virtual servers. This can streamline meeting certain PCI requirements, such as file integrity monitoring, patch management, and vulnerability management, because AWS handles these responsibilities.

Using serverless architecture on AWS can significantly reduce the PCI compliance burden. Approximately 43 percent of the overall PCI compliance requirements, encompassing both technical and non-technical tests, are addressed by the AWS PCI DSS Attestation of Compliance.

Customer responsible
52%
AWS responsible
43%
N/A
5%

The following table provides an analysis of each PCI DSS requirement against the serverless architecture in Figure 1, which shows a sample payment application workflow. You must evaluate your own use and secure configuration of AWS workload and architectures for a successful audit.

PCI DSS 4.0 requirements Test cases Customer responsible AWS responsible N/A
Requirement 1: Install and maintain network security controls 35 13 22 0
Requirement 2: Apply secure configurations to all system components 27 16 11 0
Requirement 3: Protect stored account data 55 24 29 2
Requirement 4: Protect cardholder data with strong cryptography during transmission over open, public networks 12 7 5 0
Requirement 5: Protect all systems and networks from malicious software 25 4 21 0
Requirement 6: Develop and maintain secure systems and software 35 31 4 0
Requirement 7: Restrict access to system components and cardholder data by business need-to-know 22 19 3 0
Requirement 8: Identify users and authenticate access to system components 52 43 6 3
Requirement 9: Restrict physical access to cardholder data 56 3 53 0
Requirement 10: Log and monitor all access to system components and cardholder data 38 17 19 2
Requirement 11: Test security of systems and networks regularly 51 22 23 6
Requirement 12: Support information security with organizational policies 56 44 2 10
Total 464 243 198 23
Percentage 52% 43% 5%

Note: The preceding table is based on the example reference architecture that follows. The actual extent of PCI DSS requirements reduction can vary significantly depending on your cardholder data environment (CDE) scope, implementation, and configurations.

Sample payment application and workflow

This example serverless payment application and workflow in Figure 1 consists of several interconnected steps, each using different AWS services. The steps are listed in the following text and include brief descriptions. They cover two use cases within this example application — consumers making a payment and a business analyst generating a report.

The example outlines a basic serverless payment application workflow using AWS serverless services. However, it’s important to note that the actual implementation and behavior of the workflow may vary based on specific configurations, dependencies, and external factors. The example serves as a general guide and may require adjustments to suit the unique requirements of your application or infrastructure.

Several factors, including but not limited to, AWS service configurations, network settings, security policies, and third-party integrations, can influence the behavior of the system. Before deploying a similar solution in a production environment, we recommend thoroughly reviewing and adapting the example to align with your specific use case and requirements.

Keep in mind that AWS services and features may evolve over time, and new updates or changes may impact the behavior of the components described in this example. Regularly consult the AWS documentation and ensure that your configurations adhere to best practices and compliance standards.

This example is intended to provide a starting point and should be considered as a reference rather than an exhaustive solution. Always conduct thorough testing and validation in your specific environment to ensure the desired functionality and security.

Figure 1: Serverless payment architecture and workflow

Figure 1: Serverless payment architecture and workflow

  • Use case 1: Consumers make a payment
    1. Consumers visit the e-commerce payment page to make a payment.
    2. The request is routed to the payment application’s domain using Amazon Route 53, which acts as a DNS service.
    3. The payment page is protected by AWS WAF to inspect the initial incoming request for any malicious patterns, web-based attacks (such as cross-site scripting (XSS) attacks), and unwanted bots.
    4. An HTTPS GET request (over TLS) is sent to the public target IP. Amazon CloudFront, a content delivery network (CDN), acts as a front-end proxy and caches and fetches static content from an Amazon Simple Storage Service (Amazon S3) bucket.
    5. AWS WAF inspects the incoming request for any malicious patterns, if the request is blocked, the request doesn’t return static content from the S3 bucket.
    6. User authentication and authorization are handled by Amazon Cognito, providing a secure login and scalable customer identity and access management system (CIAM)
    7. AWS WAF processes the request to protect against web exploits, then Amazon API Gateway forwards it to the payment application API endpoint.
    8. API Gateway launches AWS Lambda functions to handle payment requests. AWS Step Functions state machine oversees the entire process, directing the running of multiple Lambda functions to communicate with the payment processor, initiate the payment transaction, and process the response.
    9. The cardholder data (CHD) is temporarily cached in Amazon DynamoDB for troubleshooting and retry attempts in the event of transaction failures.
    10. A Lambda function validates the transaction details and performs necessary checks against the data stored in DynamoDB. A web notification is sent to the consumer for any invalid data.
    11. A Lambda function calculates the transaction fees.
    12. A Lambda function authenticates the transaction and initiates the payment transaction with the third-party payment provider.
    13. A Lambda function is initiated when a payment transaction with the third-party payment provider is completed. It receives the transaction status from the provider and performs multiple actions.
    14. Consumers receive real-time notifications through a web browser and email. The notifications are initiated by a step function, such as order confirmations or payment receipts, and can be integrated with external payment processors through an Amazon Simple Notification Service (Amazon SNS) Amazon Simple Email Service (Amazon SES) web hook.
    15. A separate Lambda function clears the DynamoDB cache.
    16. The Lambda function makes entries into the Amazon Simple Queue Service (Amazon SQS) dead-letter queue for failed transactions to retry at a later time.
  • Use case 2: An admin or analyst generates the report for non-PCI data
    1. An admin accesses the web-based reporting dashboard using their browser to generate a report.
    2. The request is routed to AWS WAF to verify the source that initiated the request.
    3. An HTTPS GET request (over TLS) is sent to the public target IP. CloudFront fetches static content from an S3 bucket.
    4. AWS WAF inspects incoming requests for any malicious patterns, if the request is blocked, the request doesn’t return static content from the S3 bucket. The validated traffic is sent to Amazon S3 to retrieve the reporting page.
    5. The backend requests of the reporting page pass through AWS WAF again to provide protection against common web exploits before being forwarded to the reporting API endpoint through API Gateway.
    6. API Gateway launches a Lambda function for report generation. The Lambda function retrieves data from DynamoDB storage for the reporting mechanism.
    7. The AWS Security Token Service (AWS STS) issues temporary credentials to the Lambda service in the non-PCI serverless account, allowing it to launch the Lambda function in the PCI serverless account. The Lambda function retrieves non-PCI data and writes it into DynamoDB.
    8. The Lambda function fetches the non-PCI data based on the report criteria from the DynamoDB table from the same account.

Additional AWS security and governance services that would be implemented throughout the architecture are shown in Figure 1, Label-25. For example, Amazon CloudWatch monitors and alerts on all the Lambda functions within the environment.

Label-26 demonstrates frameworks that can be used to build the serverless applications.

Scoping and requirements

Now that we’ve established the reference architecture and workflow, lets delve into how it aligns with PCI DSS scope and requirements.

PCI scoping

Serverless services are inherently segmented by AWS, but they can be used within the context of an AWS account hierarchy to provide various levels of isolation as described in the reference architecture example.

Segregating PCI data and non-PCI data into separate AWS accounts can help in de-scoping non-PCI environments and reducing the complexity and audit requirements for components that don’t handle cardholder data.

PCI serverless production account

  • This AWS account is dedicated to handling PCI data and applications that directly process, transmit, or store cardholder data.
  • Services such as Amazon Cognito, DynamoDB, API Gateway, CloudFront, Amazon SNS, Amazon SES, Amazon SQS, and Step Functions are provisioned in this account to support the PCI data workflow.
  • Security controls, logging, monitoring, and access controls in this account are specifically designed to meet PCI DSS requirements.

Non-PCI serverless production account

  • This separate AWS account is used to host applications that don’t handle PCI data.
  • Since this account doesn’t handle cardholder data, the scope of PCI DSS compliance is reduced, simplifying the compliance process.

Note: You can use AWS Organizations to centrally manage multiple AWS accounts.

AWS IAM Identity Center (successor to AWS Single Sign-On) is used to manage user access to each account and is integrated with your existing identify provider. This helps to ensure you’re meeting PCI requirements on identity, access control of card holder data, and environment.

Now, let’s look at the PCI DSS requirements that this architectural pattern can help address.

Requirement 1: Install and maintain network security controls

  • Network security controls are limited to AWS Identity and Access Management (IAM) and application permissions because there is no customer controlled or defined network. VPC-centric requirements aren’t applicable because there is no VPC. The configuration settings for serverless services can be covered under Requirement 6 to for secure configuration standards. This supports compliance with Requirements 1.2 and 1.3.

Requirement 2: Apply secure configurations to all system components

  • AWS services are single function by default and exist with only the necessary functionality enabled for the functioning of that service. This supports compliance with much of Requirement 2.2.
  • Access to AWS services is considered non-console and only accessible through HTTPS through the service API. This supports compliance with Requirement 2.2.7.
  • The wireless requirements under Requirement 2.3 are not applicable, because wireless environments don’t exist in AWS environments.

Requirement 3: Protect stored account data

  • AWS is responsible for destruction of account data configured for deletion based on DynamoDB Time to Live (TTL) values. This supports compliance with Requirement 3.2.
  • DynamoDB and Amazon S3 offer secure storage of account data, encryption by default in transit and at rest, and integration with AWS Key Management Service (AWS KMS). This supports compliance with Requirements 3.5 and 4.2.
  • AWS is responsible for the generation, distribution, storage, rotation, destruction, and overall protection of encryption keys within AWS KMS. This supports compliance with Requirements 3.6 and 3.7.
  • Manual cleartext cryptographic keys aren’t available in this solution, Requirement 3.7.6 is not applicable.

Requirement 4: Protect cardholder data with strong cryptography during transmission over open, public networks

  • AWS Certificate Manager (ACM) integrates with API Gateway and enables the use of trusted certificates and HTTPS (TLS) for secure communication between clients and the API. This supports compliance with Requirement 4.2.
  • Requirement 4.2.1.2 is not applicable because there are no wireless technologies in use in this solution. Customers are responsible for ensuring strong cryptography exists for authentication and transmission over other wireless networks they manage outside of AWS.
  • Requirement 4.2.2 is not applicable because no end-user technologies exist in this solution. Customers are responsible for ensuring the use of strong cryptography if primary account numbers (PAN) are sent through end-user messaging technologies in other environments.

Requirement 5: Protect a ll systems and networks from malicious software

  • There are no customer-managed compute resources in this example payment environment, Requirements 5.2 and 5.3 are the responsibility of AWS.

Requirement 6: Develop and maintain secure systems and software

  • Amazon Inspector now supports Lambda functions, adding continual, automated vulnerability assessments for serverless compute. This supports compliance with Requirement 6.2.
  • Amazon Inspector helps identify vulnerabilities and security weaknesses in the payment application’s code, dependencies, and configuration. This supports compliance with Requirement 6.3.
  • AWS WAF is designed to protect applications from common attacks, such as SQL injections, cross-site scripting, and other web exploits. AWS WAF can filter and block malicious traffic before it reaches the application. This supports compliance with Requirement 6.4.2.

Requirement 7: Restrict access to system components and cardholder data by business need to know

  • IAM and Amazon Cognito allow for fine-grained role- and job-based permissions and access control. Customers can use these capabilities to configure access following the principles of least privilege and need-to-know. IAM and Cognito support the use of strong identification, authentication, authorization, and multi-factor authentication (MFA). This supports compliance with much of Requirement 7.

Requirement 8: Identify users and authenticate access to system components

  • IAM and Amazon Cognito also support compliance with much of Requirement 8.
  • Some of the controls in this requirement are usually met by the identity provider for internal access to the cardholder data environment (CDE).

Requirement 9: Restrict physical access to cardholder data

  • AWS is responsible for the destruction of data in DynamoDB based on the customer configuration of content TTL values for Requirement 9.4.7. Customers are responsible for ensuring their database instance is configured for appropriate removal of data by enabling TTL on DDB attributes.
  • Requirement 9 is otherwise not applicable for this serverless example environment because there are no physical media, electronic media not already addressed under Requirement 3.2, or hard-copy materials with cardholder data. AWS is responsible for the physical infrastructure under the Shared Responsibility Model.

Requirement 10: Log and monitor all access to system components and cardholder data

  • AWS CloudTrail provides detailed logs of API activity for auditing and monitoring purposes. This supports compliance with Requirement 10.2 and contains all of the events and data elements listed.
  • CloudWatch can be used for monitoring and alerting on system events and performance metrics. This supports compliance with Requirement 10.4.
  • AWS Security Hub provides a comprehensive view of security alerts and compliance status, consolidating findings from various security services, which helps in ongoing security monitoring and testing. Customers must enable PCI DSS security standard, which supports compliance with Requirement 10.4.2.
  • AWS is responsible for maintaining accurate system time for AWS services. In this example, there are no compute resources for which customers can configure time. Requirement 10.6 is addressable through the AWS Attestation of Compliance and Responsibility Summary available in AWS Artifact.

Requirement 11: Regularly test security systems and processes

  • Testing for rogue wireless activity within the AWS-based CDE is the responsibility of AWS. AWS is responsible for the management of the physical infrastructure under Requirement 11.2. Customers are still responsible for wireless testing for their environments outside of AWS, such as where administrative workstations exist.
  • AWS is responsible for internal vulnerability testing of AWS services, and supports compliance with Requirement 11.3.1.
  • Amazon GuardDuty, a threat detection service that continuously monitors for malicious activity and unauthorized access, providing continuous security monitoring. This supports the IDS requirements under Requirement 11.5.1, and covers the entire AWS-based CDE.
  • AWS Config allows customers to catalog, monitor and manage configuration changes for their AWS resources. This supports compliance with Requirement 11.5.2.
  • Customers can use AWS Config to monitor the configuration of the S3 bucket hosting the static website. This supports compliance with Requirement 11.6.1.

Requirement 12: Support information security with organizational policies and programs

  • Customers can download the AWS AOC and Responsibility Summary package from Artifact to support Requirement 12.8.5 and the identification of which PCI DSS requirements are managed by the third-party service provider (TSPS) and which by the customer.

Conclusion

Using AWS serverless services when developing your payment application can significantly help reduce the number of PCI DSS requirements you need to meet by yourself. By offloading infrastructure management to AWS and using serverless services such as Lambda, API Gateway, DynamoDB, Amazon S3, and others, you can benefit from built-in security features and help align with your PCI DSS compliance requirements.

Contact us to help design an architecture that works for your organization. AWS Security Assurance Services is a Payment Card Industry-Qualified Security Assessor company (PCI-QSAC) and HITRUST External Assessor firm. We are a team of industry-certified assessors who help you to achieve, maintain, and automate compliance in the cloud by tying together applicable audit standards to AWS service-specific features and functionality. We help you build on frameworks such as PCI DSS, HITRUST CSF, NIST, SOC 2, HIPAA, ISO 27001, GDPR, and CCPA.

More information on how to build applications using AWS serverless technologies can be found at Serverless on AWS.

Want more AWS Security news? Follow us on Twitter.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the Serverless re:Post, Security, Identity, & Compliance re:Post or contact AWS Support.
Abdul Javid

Abdul Javid

Abdul is a Senior Security Assurance Consultant and PCI DSS Qualified Security Assessor with AWS Security Assurance Services, and has more than 25 years of IT governance, operations, security, risk, and compliance experience. Abdul leverages his experience and knowledge to advise AWS customers with guidance and advice on their compliance journey. Abdul earned an M.S. in Computer Science from IIT, Chicago and holds various industry recognized sought after certifications in security and program and risk management from prominent organizations like AWS, HITRUST, ISACA, PMI, PCI DSS, and ISC2.

Ted Tanner

Ted Tanner

Ted is a Principal Assurance Consultant and PCI DSS Qualified Security Assessor with AWS Security Assurance Services, and has more than 25 years of IT and security experience. He uses this experience to provide AWS customers with guidance on compliance and security, and on building and optimizing their cloud compliance programs. He is co-author of the Payment Card Industry Data Security Standard (PCI DSS) v3.2.1 on AWS Compliance Guide and the soon-to-be-released v4.0 edition.

Tristan Watty

Tristan Watty

Dr. Watty is a Senior Security Consultant within the Professional Services team of Amazon Web Services based in Queens, New York. He is a passionate Tech Enthusiast, Influencer, and Amazonian with 15+ years of professional and educational experience with a specialization in Security, Risk, and Compliance. His zeal lies in empowering customers to develop and put into action secure mechanisms that steer them towards achieving their security goals. Dr. Watty also created and hosts an AWS Security Show named “Security SideQuest!” that airs on the AWS Twitch Channel.

Padmakar Bhosale

Padmakar Bhosale

Padmakar is a Sr. Technical Account Manager with over 25 years of experience in the Financial, Banking, and Cloud Services. He provides AWS customers with guidance and advice on Payment Services, Core Banking Ecosystem, Credit Union Banking Technologies, Resiliency on AWS Cloud, AWS Accounts & Network levels PCI Segmentations, and Optimization of the Customer’s Cloud Journey experience on AWS Cloud.

Prepare your AWS workloads for the “Operational risks and resilience – banks” FINMA Circular

Post Syndicated from Margo Cronin original https://aws.amazon.com/blogs/security/prepare-your-aws-workloads-for-the-operational-risks-and-resilience-banks-finma-circular/

In December 2022, FINMA, the Swiss Financial Market Supervisory Authority, announced a fully revised circular called Operational risks and resilience – banks that will take effect on January 1, 2024. The circular will replace the Swiss Bankers Association’s Recommendations for Business Continuity Management (BCM), which is currently recognized as a minimum standard. The new circular also adopts the revised principles for managing operational risks, and the new principles on operational resilience, that the Basel Committee on Banking Supervision published in March 2021.

In this blog post, we share key considerations for AWS customers and regulated financial institutions to help them prepare for, and align to, the new circular.

AWS previously announced the publication of the AWS User Guide to Financial Services Regulations and Guidelines in Switzerland. The guide refers to certain rules applicable to financial institutions in Switzerland, including banks, insurance companies, stock exchanges, securities dealers, portfolio managers, trustees, and other financial entities that FINMA oversees (directly or indirectly).

FINMA has previously issued the following circulars to help regulated financial institutions understand approaches to due diligence, third party management, and key technical and organizational controls to be implemented in cloud outsourcing arrangements, particularly for material workloads:

  • 2018/03 FINMA Circular Outsourcing – banks and insurers (31.10.2019)
  • 2008/21 FINMA Circular Operational Risks – Banks (31.10.2019) – Principal 4 Technology Infrastructure
  • 2008/21 FINMA Circular Operational Risks – Banks (31.10.2019) – Appendix 3 Handling of electronic Client Identifying Data
  • 2013/03 Auditing (04.11.2020) – Information Technology (21.04.2020)
  • BCM minimum standards proposed by the Swiss Insurance Association (01.06.2015) and Swiss Bankers Association (29.08.2013)

Operational risk management: Critical data

The circular defines critical data as follows:

“Critical data are data that, in view of the institution’s size, complexity, structure, risk profile and business model, are of such crucial significance that they require increased security measures. These are data that are crucial for the successful and sustainable provision of the institution’s services or for regulatory purposes. When assessing and determining the criticality of data, the confidentiality as well as the integrity and availability must be taken into account. Each of these three aspects can determine whether data is classified as critical.”

This definition is consistent with the AWS approach to privacy and security. We believe that for AWS to realize its full potential, customers must have control over their data. This includes the following commitments:

  • Control over the location of your data
  • Verifiable control over data access
  • Ability to encrypt everything everywhere
  • Resilience of AWS

These commitments further demonstrate our dedication to securing your data: it’s our highest priority. We implement rigorous contractual, technical, and organizational measures to help protect the confidentiality, integrity, and availability of your content regardless of which AWS Region you select. You have complete control over your content through powerful AWS services and tools that you can use to determine where to store your data, how to secure it, and who can access it.

You also have control over the location of your content on AWS. For example, in Europe, at the time of publication of this blog post, customers can deploy their data into any of eight Regions (for an up-to-date list of Regions, see AWS Global Infrastructure). One of these Regions is the Europe (Zurich) Region, also known by its API name ‘eu-central-2’, which customers can use to store data in Switzerland. Additionally, Swiss customers can rely on the terms of the AWS Swiss Addendum to the AWS Data Processing Addendum (DPA), which applies automatically when Swiss customers use AWS services to process personal data under the new Federal Act on Data Protection (nFADP).

AWS continually monitors the evolving privacy, regulatory, and legislative landscape to help identify changes and determine what tools our customers might need to meet their compliance requirements. Maintaining customer trust is an ongoing commitment. We strive to inform you of the privacy and security policies, practices, and technologies that we’ve put in place. Our commitments, as described in the Data Privacy FAQ, include the following:

  • Access – As a customer, you maintain full control of your content that you upload to the AWS services under your AWS account, and responsibility for configuring access to AWS services and resources. We provide an advanced set of access, encryption, and logging features to help you do this effectively (for example, AWS Identity and Access Management, AWS Organizations, and AWS CloudTrail). We provide APIs that you can use to configure access control permissions for the services that you develop or deploy in an AWS environment. We never use your content or derive information from it for marketing or advertising purposes.
  • Storage – You choose the AWS Regions in which your content is stored. You can replicate and back up your content in more than one Region. We will not move or replicate your content outside of your chosen AWS Regions except as agreed with you.
  • Security – You choose how your content is secured. We offer you industry-leading encryption features to protect your content in transit and at rest, and we provide you with the option to manage your own encryption keys. These data protection features include:
  • Disclosure of customer content – We will not disclose customer content unless we’re required to do so to comply with the law or a binding order of a government body. If a governmental body sends AWS a demand for your customer content, we will attempt to redirect the governmental body to request that data directly from you. If compelled to disclose your customer content to a governmental body, we will give you reasonable notice of the demand to allow the customer to seek a protective order or other appropriate remedy, unless AWS is legally prohibited from doing so.
  • Security assurance – We have developed a security assurance program that uses current recommendations for global privacy and data protection to help you operate securely on AWS, and to make the best use of our security control environment. These security protections and control processes are independently validated by multiple third-party independent assessments, including the FINMA International Standard on Assurance Engagements (ISAE) 3000 Type II attestation report.

Additionally, FINMA guidelines lay out requirements for the written agreement between a Swiss financial institution and its service provider, including access and audit rights. For Swiss financial institutions that run regulated workloads on AWS, we offer the Swiss Financial Services Addendum to address the contractual and audit requirements of the FINMA guidelines. We also provide these institutions the ability to comply with the audit requirements in the FINMA guidelines through the AWS Security & Audit Series, including participation in an Audit Symposium, to facilitate customer audits. To help align with regulatory requirements and expectations, our FINMA addendum and audit program incorporate feedback that we’ve received from a variety of financial supervisory authorities across EU member states. To learn more about the Swiss Financial Services addendum or about the audit engagements offered by AWS, reach out to your AWS account team.

Resilience

Customers need control over their workloads and high availability to help prepare for events such as supply chain disruptions, network interruptions, and natural disasters. Each AWS Region is composed of multiple Availability Zones (AZs). An Availability Zone is one or more discrete data centers with redundant power, networking, and connectivity in an AWS Region. To better isolate issues and achieve high availability, you can partition applications across multiple AZs in the same Region. If you are running workloads on premises or in intermittently connected or remote use cases, you can use our services that provide specific capabilities for offline data and remote compute and storage. We will continue to enhance our range of sovereign and resilient options, to help you sustain operations through disruption or disconnection.

FINMA incorporates the principles of operational resilience in the newest circular 2023/01. In line with the efforts of the European Commission’s proposal for the Digital Operational Resilience Act (DORA), FINMA outlines requirements for regulated institutions to identify critical functions and their tolerance for disruption. Continuity of service, especially for critical economic functions, is a key prerequisite for financial stability. AWS recognizes that financial institutions need to comply with sector-specific regulatory obligations and requirements regarding operational resilience. AWS has published the whitepaper Amazon Web Services’ Approach to Operational Resilience in the Financial Sector and Beyond, in which we discuss how AWS and customers build for resiliency on the AWS Cloud. AWS provides resilient infrastructure and services, which financial institution customers can rely on as they design their applications to align with FINMA regulatory and compliance obligations.

AWS previously announced the third issuance of the FINMA ISAE 3000 Type II attestation report. Customers can access the entire report in AWS Artifact. To learn more about the list of certified services and Regions, see the FINMA ISAE 3000 Type 2 Report and AWS Services in Scope for FINMA.

AWS is committed to adding new services into our future FINMA program scope based on your architectural and regulatory needs. If you have questions about the FINMA report, or how your workloads on AWS align to the FINMA obligations, contact your AWS account team. We will also help support customers as they look for new ways to experiment, remain competitive, meet consumer expectations, and develop new products and services on AWS that align with the new regulatory framework.

To learn more about our compliance, security programs and common privacy and data protection considerations, see AWS Compliance Programs and the dedicated AWS Compliance Center for Switzerland. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the Security, Identity, & Compliance re:Post or contact AWS Support.

Margo Cronin

Margo Cronin

Margo is an EMEA Principal Solutions Architect specializing in security and compliance. She is based out of Zurich, Switzerland. Her interests include security, privacy, cryptography, and compliance. She is passionate about her work unblocking security challenges for AWS customers, enabling their successful cloud journeys. She is an author of AWS User Guide to Financial Services Regulations and Guidelines in Switzerland.

Raphael Fuchs

Raphael Fuchs

Raphael is a Senior Security Solutions Architect based in Zürich, Switzerland, who helps AWS Financial Services customers meet their security and compliance objectives in the AWS Cloud. Raphael has a background as Chief Information Security Officer in the Swiss FSI sector and is an author of AWS User Guide to Financial Services Regulations and Guidelines in Switzerland.

Scaling national identity schemes with itsme and Amazon Cognito

Post Syndicated from Guillaume Neau original https://aws.amazon.com/blogs/security/scaling-national-identity-schemes-with-itsme-and-amazon-cognito/

In this post, we demonstrate how you can use identity federation and integration between the identity provider itsme® and Amazon Cognito to quickly consume and build digital services for citizens on Amazon Web Services (AWS) using available national digital identities. We also provide code examples and integration proofs of concept to get you started quickly.

National digital identities refer to a system or framework that a government establishes to uniquely and securely identify its citizens or residents in the digital realm.

These national digital identities are built on a rigorous process of identity verification and enforce the use of high security standards when it comes to authentication mechanisms. Their adoption by both citizens and businesses helps to fight identity theft, most notably by removing the need to send printed copies of identity documents.

National certified secure digital identities are suitable for both businesses and public services and can improve the onboarding experience by reducing the need to create new credentials.

About itsme

itsme is a trusted identity provider (certified and notified for all 27 member states of EU at Level of Assurance HIGH of the eiDAS regulation) that can be used on over 800 government and company platforms to identify yourself online, log in, confirm transactions, or sign documents. It allows partners to use its verified identities for authentication and authorization on web, desktop, mobile web, and mobile applications.

As of this writing, itsme is accessible for all residents in Belgium, The Netherlands, and Luxembourg. However, since there are no limitations on the geographic usage of the identity and electronic signature APIs, itsme has the potential to expand to additional countries in the future. (Source: itsme, 2023)

Architecture overview

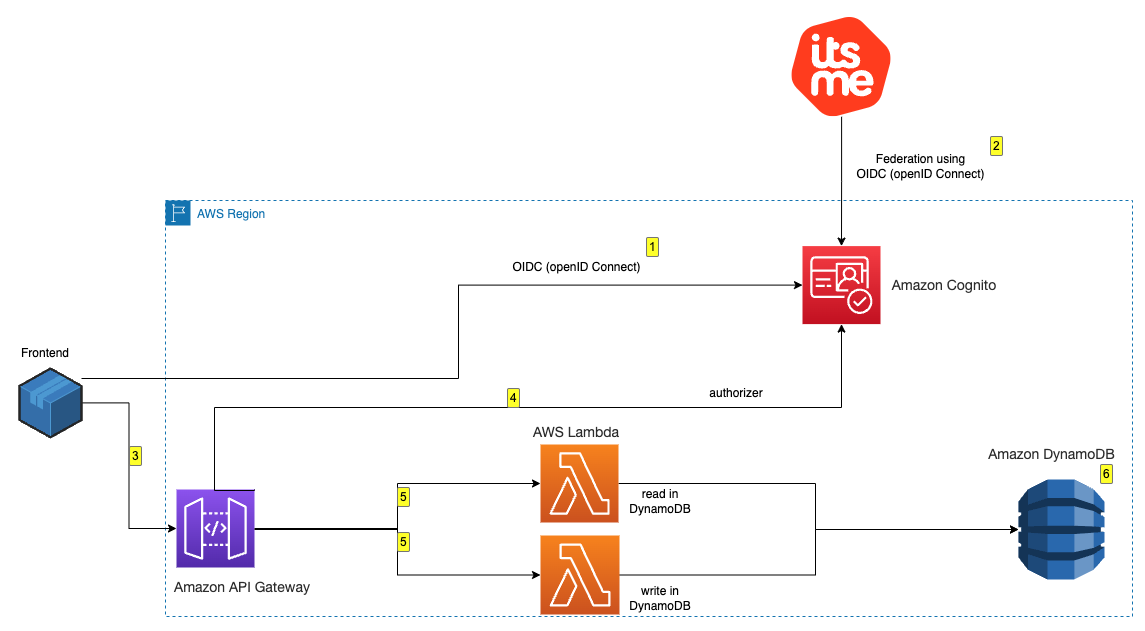
To demonstrate the integration, you’re going to build a minimalistic application made of the following components as shown in Figure 1 that follows:

Figure 1: Architectural diagram

Figure 1: Architectural diagram

After deployment, you can log in and interact with the application:

  1. Visit the frontend deployed locally, and you’re presented the option to authenticate with itsme by using a blue colored button. Choose the button to proceed.
  2. After being redirected to itsme, you’re asked to either create a new account or to use an existing one for authentication. After you’re successfully authenticated with itsme, the associated Amazon Cognito user pool is populated with the requested data in the scope of the federation. Specifically in this example, the national registration number is made available.
  3. When authenticated, you’re redirected to the frontend, and you can read and write messages to and from the database behind an Amazon API Gateway.
  4. The Amazon API Gateway uses Amazon Cognito to check the validity of your authentication token.
  5. The Lambda function reads and writes messages to and from DynamoDB.

Prerequisites to deploy the identity federation with itsme

While setting up the Amazon Cognito user pool, you’re asked for the following information:

  • An itsme client ID – itsmeClientId
  • An itsme client secret – itsmeClientSecret
  • An itsme service code – itsmeServiceCode
  • An itsme issuer URL – itsmeIssuerUrl

To retrieve this information, you must be an itsme partner and to have your sandbox requested and available. The sandbox should be made available three business days after you submit the dedicated request form to itsme.

After the sandbox is provisioned, you must contact the itsme support desk and ask to switch the sandbox authentication to the client secret – itsmeClientSecret flow. Include the link to this post and specify that it’s for establishing a federation with Amazon Cognito.

Implement the proof of concept

To implement this proof of concept, you need to follow these steps:

  1. Create an Amazon Cognito user pool.
  2. Configure the Amazon Cognito user pool.
  3. Deploy a sample API.
  4. Configure your application.

To create and configure an Amazon Cognito user pool

  1. Sign in to the AWS Management Console and enter cognito in the search bar at the top. Select Cognito from the Services results.
    Figure 2: Select Cognito service

    Figure 2: Select Cognito service

  2. In the Amazon Cognito console, select User pools, and then choose Create user pool.
    Figure 3: Cognito user pool creation

    Figure 3: Cognito user pool creation

  3. To configure the sign-in experience section, select Federated identity providers as the authentication providers.
  4. In the Cognito user pool sign-in options area, select User name, Email, and Phone number.
  5. In the Federated sign-in options area, select OpenID Connect (OIDC).
    Figure 4: Sign-in configuration

    Figure 4: Sign-in configuration

  6. Choose Next to continue to security requirements.

Note: In this post, account management and authentication are restricted to itsme. Because of this, the password length, multi-factor authentication, and recovery procedures are delegated to itsme. If you don’t restrict your Cognito user pool to itsme only, configure it according to your security requirements.

To configure the security requirements

  1. For Password policy, select Cognito defaults.
  2. Select Require MFA – Recommended in the Multi-factor authentication area, and select Authenticator apps

    Note: Although the activation of multi-factor authentication is recommended, it’s important to understand that users of this pool will be created and authenticated through the federation with itsme. In the next procedure, you disable the Self service sign-up feature to prevent users from creating accounts. As itsme is compliant with the level of assurance substantial of the eIDAS regulation, itsme users must log in using a second factor of authentication.

  3. Clear Enable self-service account recovery in the User account recovery area.
Figure 5: Security requirements configuration

Figure 5: Security requirements configuration

To configure the sign-up experience

  1. Clear Enable self-registration.
  2. Clear Allow Cognito to automatically send messages to verify and confirm.
    Figure 6: Sign-up configuration

    Figure 6: Sign-up configuration

  3. Skip the configuration of required attributes and configure custom attributes. Expand the drop-down menu and add the following custom attributes:
    1. Name: eid.
    2. Type: String.
    3. Leave Min and Max length blank.
    4. Mutable: Select.

    This custom attribute is used to map and store the national registration number.

  4. Choose Next to configure message delivery.

Note: In this post, account management and authentication are going to be restricted to itsme. As a result, Amazon Cognito doesn’t send email or SMS, and the prescribed configuration is minimal. If you don’t limit your user pool to itsme, configure message delivery parameters according to your corporate policy.

To configure message delivery

  1. For Email, select Send email with Cognito and leave the other fields with their default configuration.
  2. To configure the SMS, select Create a new IAM Role if you don’t already have one provisioned.
  3. Choose Next to configure the federated identity provider.
    Figure 7: Message delivery configuration

    Figure 7: Message delivery configuration

  4. Choose Next to configure identity provider.

To configure the federated identity provider

  1. For Provider name, enter itsme.
  2. For Client ID, enter the client ID provided by itsme.
  3. For Client secret, enter the client secret provided by itsme.
  4. For Authorized scopes, start with the mandatory service:itsmeServiceCode.
  5. With a space between each scope, enter openid profile eid email address.
  6. For Retrieve OIDC endpoints, enter the issuer URL provided by itsme.
    Figure 8: OIDC federation configuration

    Figure 8: OIDC federation configuration

    The configuration of the mapping of the attributes can be done according to the documentation provided by itsme.

    An example of mapping is provided in Figure 9 that follows. Some differences exist to be able to retrieve and map the eID and the unique username of itsme (sub).

    More specifically, to retrieve the National Registration Number, the eid field needs to be set to http://itsme.services/v2/claim/BENationalNumber.

    Figure 9: Attributes mapping

    Figure 9: Attributes mapping

  7. Choose Next to configure an app client.

To configure an app client

  1. Configure both your user pool name and domain by opening the Amazon Cognito console.
    Figure 10: User pool and domain name

    Figure 10: User pool and domain name

  2. In the Initial app client area, select Public client.
    1. Enter your application client name.
    2. Select Don’t generate a client secret.
    3. Enter the application callback URL that’s used by itsme at the end of the authenticating flow. This URL is the one your end user is going to land on after authenticating.
    Figure 11: Configuring app client

    Figure 11: Configuring app client

To finish the creation by reviewing and creating the user pool

When the user pool is created, send your Amazon Cognito domain name to itsme support for them to activate your authentication endpoints. That URL has the following composition:

https://<Your user pool domain>.auth.<your region>.amazoncognito.com/oauth2/idpresponse

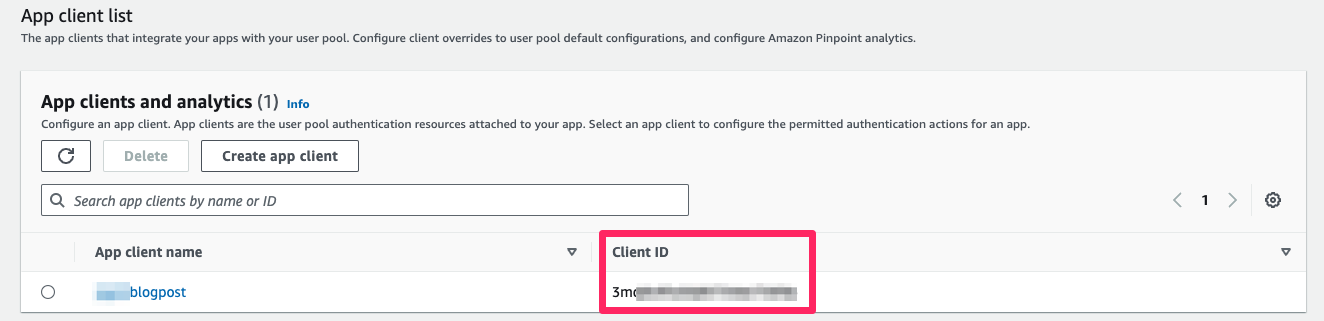
When the user pool is created, you can retrieve your userPoolWebClientId, which is required to create a consuming application.

To retrieve your userPoolWebClientId

  1. From the Amazon Cognito Console, select User pools on the left menu.
  2. Select the user pool that you created.
    Figure 12: User pool app integration

    Figure 12: User pool app integration

In the App integration area, your userPoolWebClientId is displayed at the bottom of the window.

Figure 13: Client ID

Figure 13: Client ID

To create a consuming application

When the setup of the user pool is done, you can integrate the authenticating flow in your application. The integration can be done using the AWS Amplify SDK and by calling the relevant API directly. Depending of the framework you used when building the application, you can find documentation about doing so in AWS Prescriptive Guidance Patterns.

You can use Amazon API Gateway to quickly build a secure API that uses the authentication made through Amazon Cognito and the federation to build services. We encourage you to review the Amazon API Gateway documentation to learn more. The next section provides you with examples that you can deploy to get an idea of the integration steps.

Additionally, you can use an Amazon Cognito identity pool to exchange Amazon Cognito issued tokens for AWS credentials (in other words, assuming AWS Identity and Access Management (IAM) roles) to access other AWS services. As an example, this could allow users to upload files to an Amazon Simple Storage Service (Amazon S3) bucket.

About the examples provided

The public GitHub repository that is provided contains code examples and associated documentation to help you automatically go through the setup steps detailed in this post. Specifically, the following are available:

  1. An AWS Cloudformation template that can help you provision a properly set-up user pool after you have the required information from itsme.
  2. An AWS Cloudformation template that deploys the backend for the test application.
  3. A React frontend that you can run locally to interact with the backend and to consume identities from itsme.

To deploy the provided examples

  1. Clone the repository on your local machine.
  2. Install the dependencies.
  3. If you haven’t created your user pool following the instructions in this post, you can use the CognitoItsmeStack provided as an example.
  4. Deploy the associated backend stack BackendItsmeStack.cfn.yaml.
  5. Rename the frontend/src/config.json.template file to frontend/src/config.json and replace the following:
    1. region with the AWS Region associated with your Amazon Cognito user pool.
    2. userPoolId with the assigned ID of the user pool that you created.
    3. userPoolWebClientId with the client ID that you retrieved.
    4. domain with your Amazon Cognito domain in the form of <your user pool name>.auth.<your region>.amazoncognito.com
    Figure 14: Frontend configuration file

    Figure 14: Frontend configuration file

  6. After modifications are done, start the application on your local machine with the provided command.

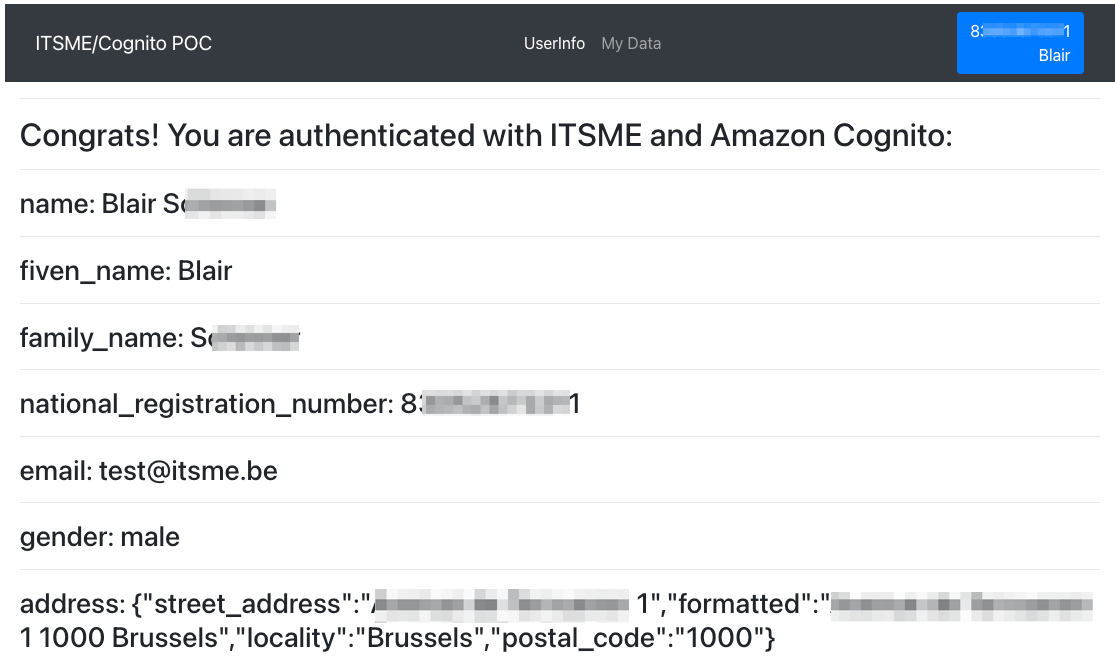
Following authentication, the results in the associated collected data are displayed, as shown in Figure 15 that follows.

Figure 15: User information

Figure 15: User information

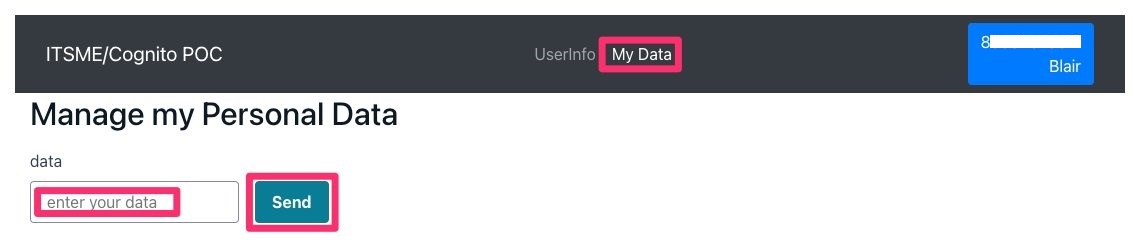
In the My Data section, you can access a form to input a value (shown in Figure 16). Each time you go back to this page, the previous value entered is shown in the input box. This input is associated with your NRN (custom:eid), and only you can access it.

Figure 16: Database interaction

Figure 16: Database interaction

Conclusion

You can now consume digital identities through identity federation between Amazon Cognito and itsme. We hope that it helps you build secure digital services to improve the life of Benelux users.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.

Guillaume Neau

Guillaume is a Solutions Architect from France with expertise in information security that focuses on building solutions that improve customers’ lives.bio text

Julien Martin

Julien Martin

Julien is a Solutions Architect at Amazon Web Services (AWS) supporting public institutions (such as local governments and cities) in Benelux. He has over 20 years of industry experience in helping customers design, build, implement, and operate enterprise applications.

Evolving cyber threats demand new security approaches – The benefits of a unified and global IT/OT SOC

Post Syndicated from Stuart Gregg original https://aws.amazon.com/blogs/security/evolving-cyber-threats-demand-new-security-approaches-the-benefits-of-a-unified-and-global-it-ot-soc/

In this blog post, we discuss some of the benefits and considerations organizations should think through when looking at a unified and global information technology and operational technology (IT/OT) security operations center (SOC). Although this post focuses on the IT/OT convergence within the SOC, you can use the concepts and ideas discussed here when thinking about other environments such as hybrid and multi-cloud, Industrial Internet of Things (IIoT), and so on.

The scope of assets has vastly expanded as organizations transition to remote work, and from increased interconnectivity through the Internet of Things (IoT) and edge devices coming online from around the globe, such as cyber physical systems. For many organizations, the IT and OT SOCs were separate, but there is a strong argument for convergence, which provides better context for the business outcomes of being able to respond to unexpected activity. In the ten security golden rules for IIoT solutions, AWS recommends deploying security audit and monitoring mechanisms across OT and IIoT environments, collecting security logs, and analyzing them using security information and event management (SIEM) tools within a SOC. SOCs are used to monitor, detect, and respond; this has traditionally been done separately for each environment. In this blog post, we explore the benefits and potential trade-offs of the convergence of these environments for the SOC. Although organizations should carefully consider the points raised throughout this blog post, the benefits of a unified SOC outweigh the potential trade-offs—visibility into the full threat chain propagating from one environment to another is critical for organizations as daily operations become more connected across IT and OT.

Traditional IT SOC

Traditionally, the SOC was responsible for security monitoring, analysis, and incident management of the entire IT environment within an organization—whether on-premises or in a hybrid architecture. This traditional approach has worked well for many years and ensures the SOC has the visibility to effectively protect the IT environment from evolving threats.

Note: Organizations should be aware of the considerations for security operations in the cloud which are discussed in this blog post.

Traditional OT SOC

Traditionally, OT, IT, and cloud teams have worked on separate sides of the air gap as described in the Purdue model. This can result in siloed OT, IIoT, and cloud security monitoring solutions, creating potential gaps in coverage or missing context that could otherwise have improved the response capability. To realize the full benefits of IT/OT convergence, IIoT, IT and OT must collaborate effectively to provide a broad perspective and the most effective defense. The convergence trend applies to newly connected devices and to how security and operations work together.

As organizations explore how industrial digital transformation can give them a competitive advantage, they’re using IoT, cloud computing, artificial intelligence and machine learning (AI/ML), and other digital technologies. This increases the potential threat surface that organizations must protect and requires a broad, integrated, and automated defense-in-depth security approach delivered through a unified and global SOC.

Without full visibility and control of traffic entering and exiting OT networks, the operations function might not be able to get full context or information that can be used to identify unexpected events. If a control system or connected assets such as programmable logic controllers (PLCs), operator workstations, or safety systems are compromised, threat actors could damage critical infrastructure and services or compromise data in IT systems. Even in cases where the OT system isn’t directly impacted, the secondary impacts can result in OT networks being shut down due to safety concerns over the ability to operate and monitor OT networks.

The SOC helps improve security and compliance by consolidating key security personnel and event data in a centralized location. Building a SOC is significant because it requires a substantial upfront and ongoing investment in people, processes, and technology. However, the value of an improved security posture is of great consideration compared to the costs.

In many OT organizations, operators and engineering teams may not be used to focusing on security; in some cases, organizations set up an OT SOC that’s independent from their IT SOC. Many of the capabilities, strategies, and technologies developed for enterprise and IT SOCs apply directly to the OT environment, such as security operations (SecOps) and standard operating procedures (SOPs). While there are clearly OT-specific considerations, the SOC model is a good starting point for a converged IT/OT cybersecurity approach. In addition, technologies such as a SIEM can help OT organizations monitor their environment with less effort and time to deliver maximum return on investment. For example, by bringing IT and OT security data into a SIEM, IT and OT stakeholders share access to the information needed to complete security work.

Benefits of a unified SOC

A unified SOC offers numerous benefits for organizations. It provides broad visibility across the entire IT and OT environments, enabling coordinated threat detection, faster incident response, and immediate sharing of indicators of compromise (IoCs) between environments. This allows for better understanding of threat paths and origins.

Consolidating data from IT and OT environments in a unified SOC can bring economies of scale with opportunities for discounted data ingestion and retention. Furthermore, managing a unified SOC can reduce overhead by centralizing data retention requirements, access models, and technical capabilities such as automation and machine learning.

Operational key performance indicators (KPIs) developed within one environment can be used to enhance another, promoting operational efficiency such as reducing mean time to detect security events (MTTD). A unified SOC enables integrated and unified security, operations, and performance, which supports comprehensive protection and visibility across technologies, locations, and deployments. Sharing lessons learned between IT and OT environments improves overall operational efficiency and security posture. A unified SOC also helps organizations adhere to regulatory requirements in a single place, streamlining compliance efforts and operational oversight.

By using a security data lake and advanced technologies like AI/ML, organizations can build resilient business operations, enhancing their detection and response to security threats.

Creating cross-functional teams of IT and OT subject matter experts (SMEs) help bridge the cultural divide and foster collaboration, enabling the development of a unified security strategy. Implementing an integrated and unified SOC can improve the maturity of industrial control systems (ICS) for IT and OT cybersecurity programs, bridging the gap between the domains and enhancing overall security capabilities.

Considerations for a unified SOC

There are several important aspects of a unified SOC for organizations to consider.

First, the separation of duty is crucial in a unified SOC environment. It’s essential to verify that specific duties are assigned to individuals based on their expertise and job function, allowing the most appropriate specialists to work on security events for their respective environments. Additionally, the sensitivity of data must be carefully managed. Robust access and permissions management is necessary to restrict access to specific types of data, maintaining that only authorized analysts can access and handle sensitive information. You should implement a clear AWS Identity and Access Management (IAM) strategy following security best practices across your organization to verify that the separation of duties is enforced.

Another critical consideration is the potential disruption to operations during the unification of IT and OT environments. To promote a smooth transition, careful planning is required to minimize any loss of data, visibility, or disruptions to standard operations. It’s crucial to recognize the differences in IT and OT security. The unique nature of OT environments and their close ties to physical infrastructure require tailored cybersecurity strategies and tools that address the distinct missions, challenges, and threats faced by industrial organizations. A copy-and-paste approach from IT cybersecurity programs will not suffice.

Furthermore, the level of cybersecurity maturity often varies between IT and OT domains. Investment in cybersecurity measures might differ, resulting in OT cybersecurity being relatively less mature compared to IT cybersecurity. This discrepancy should be considered when designing and implementing a unified SOC. Baselining the technology stack from each environment, defining clear goals and carefully architecting the solution can help ensure this discrepancy has been accounted for. After the solution has moved into the proof-of-concept (PoC) phase, you can start to testing for readiness to move the convergence to production.

You also must address the cultural divide between IT and OT teams. Lack of alignment between an organization’s cybersecurity policies and procedures with ICS and OT security objectives can impact the ability to secure both environments effectively. Bridging this divide through collaboration and clear communication is essential. This has been discussed in more detail in the post on managing organizational transformation for successful IT/OT convergence.

Unified IT/OT SOC deployment:

Figure 1 shows the deployment that would be expected in a unified IT/OT SOC. This is a high-level view of a unified SOC. In part 2 of this post, we will provide prescriptive guidance on how to design and build a unified and global SOC on AWS using AWS services and AWS Partner Network (APN) solutions.

Figure 1: Unified IT/OT SOC architecture

Figure 1: Unified IT/OT SOC architecture

The parts of the IT/OT unified SOC are the following:

Environment: There are multiple environments, including a traditional IT on-premises organization, OT environment, cloud environment, and so on. Each environment represents a collection of security events and log sources from assets.

Data lake: A centralized place for data collection, normalization, and enrichment to verify that raw data from the different environments is standardized into a common scheme. The data lake should support data retention and archiving for long term storage.

Visualize: The SOC includes multiple dashboards based on organizational and operational needs. Dashboards can cover scenarios for multiple environments including data flows between IT and OT environments. There are also specific dashboards for the individual environments to cover each stakeholder’s needs. Data should be indexed in a way that allows humans and machines to query the data to monitor for security and performance issues.

Security analytics: Security analytics are used to aggregate and analyze security signals and generate higher fidelity alerts and to contextualize OT signals against concurrent IT signals and against threat intelligence from reputable sources.

Detect, alert, and respond: Alerts can be set up for events of interest based on data across both individual and multiple environments. Machine learning should be used to help identify threat paths and events of interest across the data.

Conclusion

Throughout this blog post, we’ve talked through the convergence of IT and OT environments from the perspective of optimizing your security operations. We looked at the benefits and considerations of designing and implementing a unified SOC.

Visibility into the full threat chain propagating from one environment to another is critical for organizations as daily operations become more connected across IT and OT. A unified SOC is the nerve center for incident detection and response and can be one of the most critical components in improving your organization’s security posture and cyber resilience.

If unification is your organization’s goal, you must fully consider what this means and design a plan for what a unified SOC will look like in practice. Running a small proof of concept and migrating in steps often helps with this process.

In the next blog post, we will provide prescriptive guidance on how to design and build a unified and global SOC using AWS services and AWS Partner Network (APN) solutions.

Learn more:

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Stuart Gregg

Stuart Gregg

Stuart enjoys providing thought leadership and being a trusted advisor to customers. In his spare time, Stuart can be seen either training for an Ironman or snacking.

Ryan Dsouza

Ryan Dsouza

Ryan is a Principal IIoT Security Solutions Architect at AWS. Based in New York City, Ryan helps customers design, develop, and operate more secure, scalable, and innovative IIoT solutions using AWS capabilities to deliver measurable business outcomes. Ryan has over 25 years of experience in multiple technology disciplines and industries and is passionate about bringing security to connected devices.

An automated approach to perform an in-place engine upgrade in Amazon OpenSearch Service

Post Syndicated from Prashant Agrawal original https://aws.amazon.com/blogs/big-data/an-automated-approach-to-perform-an-in-place-engine-upgrade-in-amazon-opensearch-service/

Software upgrades bring new features and better performance, and keep you current with the software provider. However, upgrades for software services can be difficult to complete successfully, especially when you can’t tolerate downtime and when the new version’s APIs introduce breaking changes and deprecation that you must remediate. This post shows you how to upgrade from Elasticsearch engine to OpenSearch engine on Amazon OpenSearch Service without needing an intermediate upgrade to Elasticsearch 7.10.

OpenSearch Service supports OpenSearch as an engine, with versions in the 1.x through 2.x series. The service also supports legacy versions of Elasticsearch, versions 1.x through 7.10. Although OpenSearch brings many improvements over earlier engines, it can feel daunting to consider not only upgrading versions, but also changing engines in the process. The good news is that OpenSearch 1.0 is wire compatible with Elasticsearch 7.10, making engine changes straightforward. If you’re running a version of Elasticsearch in the 6.x or early 7.x series on OpenSearch Service, you might think you need to upgrade to Elasticsearch 7.10, and then upgrade to OpenSearch 1.3. However, you can easily upgrade your existing Elasticsearch engine running 6.8, 7.1, 7.2, 7.4, 7.9, and 7.10 in OpenSearch Service to the OpenSearch 1.3 engine.

OpenSearch Service runs a variety of checks before running an actual upgrade:

  • Validation before starting an upgrade
  • Preparing the setup configuration for the desired version
  • Provisioning new nodes with the same hardware configuration
  • Moving shards from old nodes to newly provisioned nodes
  • Removing older nodes and old node references from OpenSearch endpoints

During an upgrade, AWS takes care of the undifferentiated heavy lifting of provisioning, deploying, and moving the data to new domain. You are responsible to make sure there are no breaking changes that affect the data migration and movement to the newer version of the OpenSearch domain. In this post, we discuss the things you must modify and verify before and after running an upgrade from 6.8, 7.1, 7.2, 7.4, 7.9, and 7.10 version of Elasticsearch to 1.3 OpenSearch Service.

Pre-upgrade breaking changes

The following are pre-upgrade breaking changes:

  • Dependency check for language clients and libraries – If you’re using the open-source high-level language clients from Elastic, for example the Java, go, or Python client libraries, AWS recommends moving to the open-source, OpenSearch versions of these clients. (If you don’t use a high-level language client, you can skip this step.) The following are a few steps to perform a dependency check:
    • Determine the client library – Choose an appropriate client library compatible with your programing language. Refer to OpenSearch language clients for a list of all supported client libraries.
    • Add dependencies and resolve conflicts – Update your project’s dependency management system with the necessary dependencies specified by the client library. If your project already has dependencies that conflict with the OpenSearch client library dependencies, you may encounter dependency conflicts. In such cases, you need to resolve the conflicts manually.
    • Test and verify the client – Test the OpenSearch client functionality by establishing a connection, performing some basic operations (like indexing and searching), and verifying the results.
  • Removal of mapping types – Multiple types within an index were deprecated in Elasticsearch version 6.x, and completely removed in version 7.0 or later. OpenSearch indexes can only contain one mapping type. From OpenSearch version 2.x onward, the mapping _type must be _doc. You must check and fix the mapping before upgrading to OpenSearch 1.3.

Complete the following steps to identify and fix mapping issues:

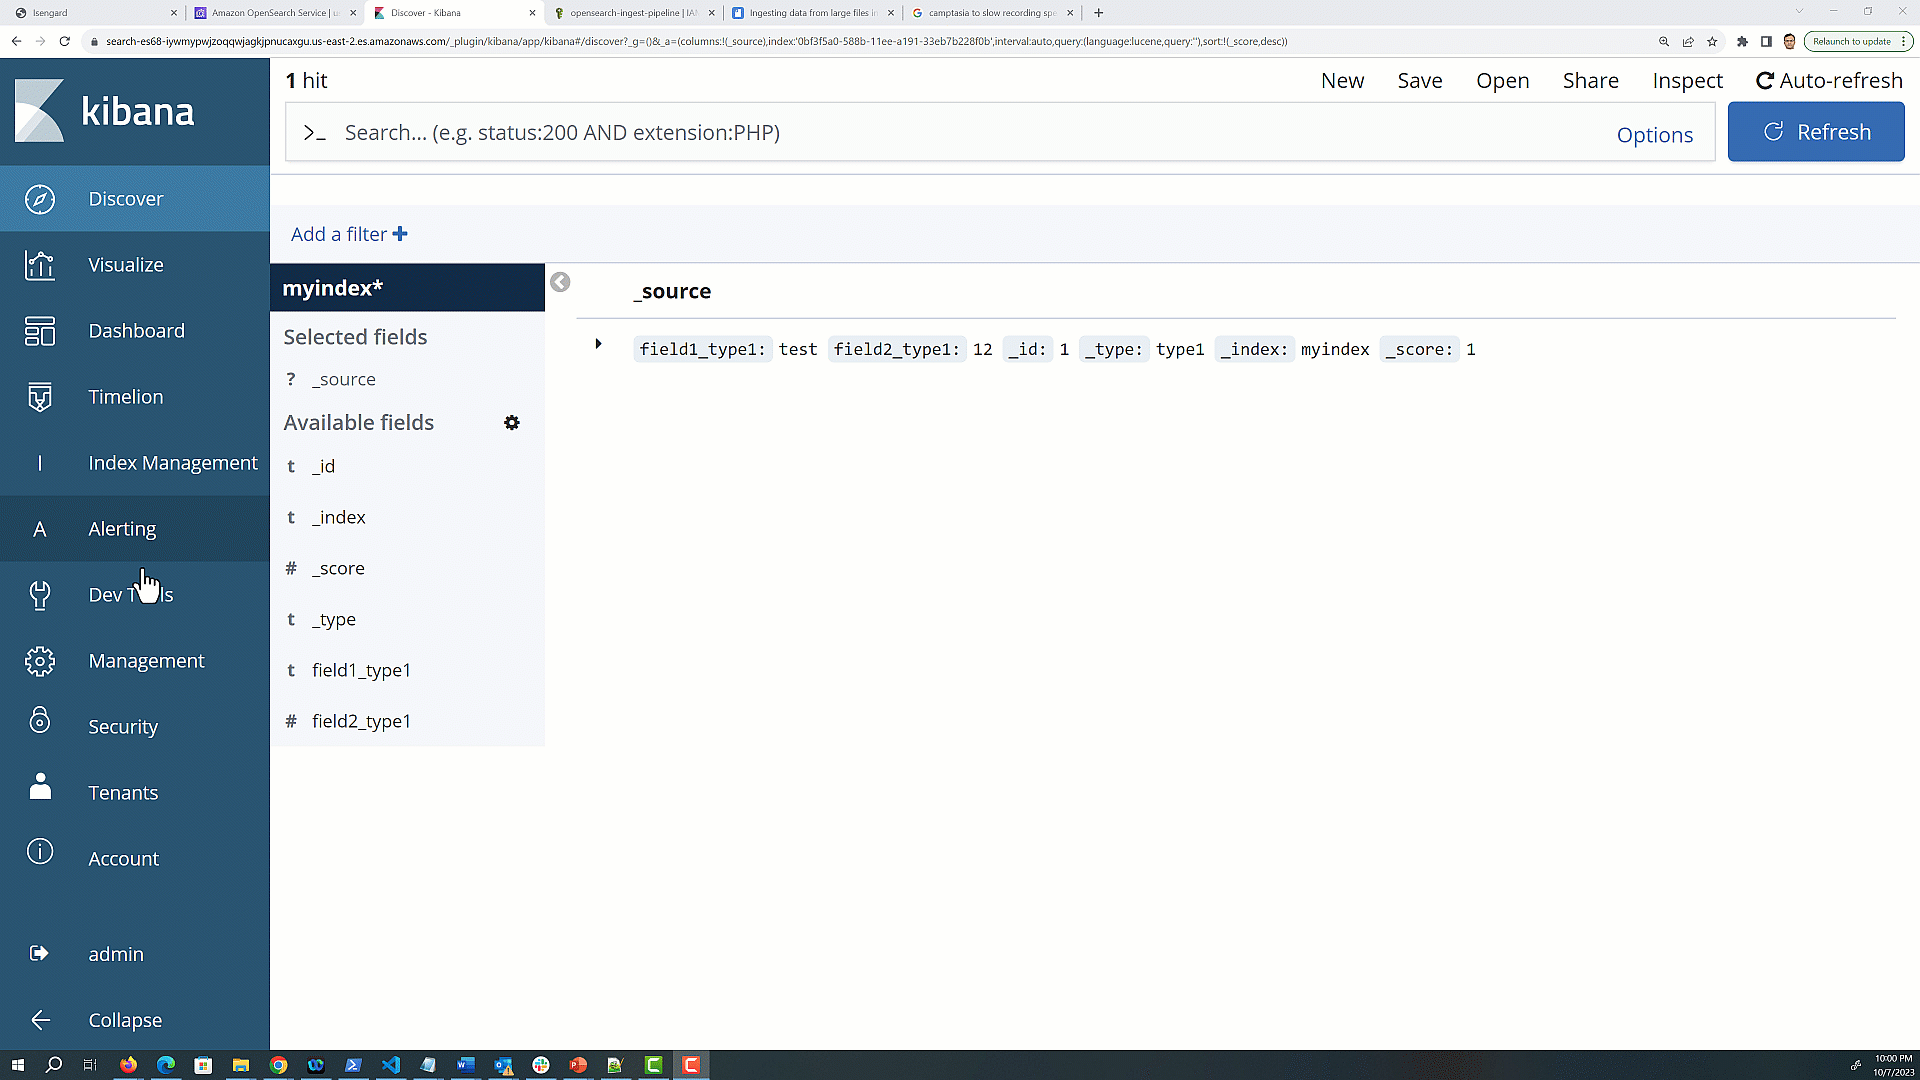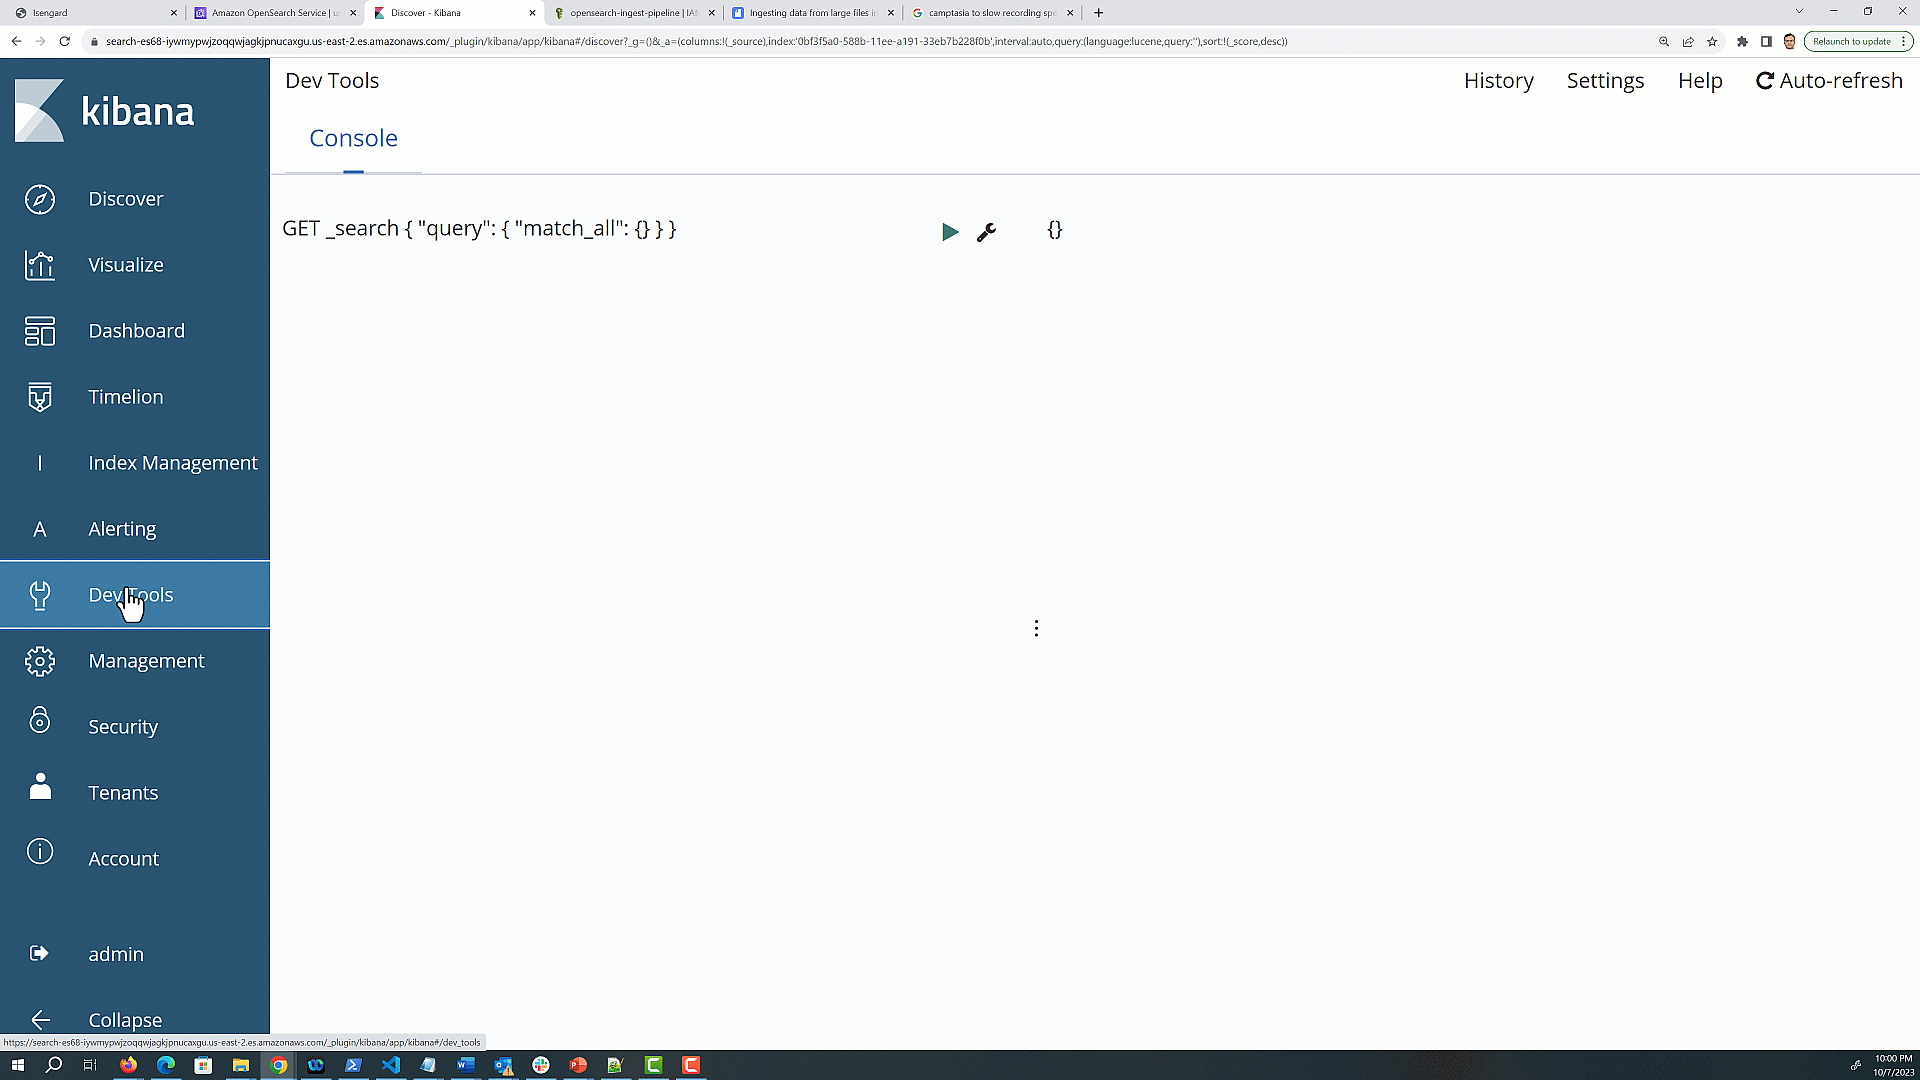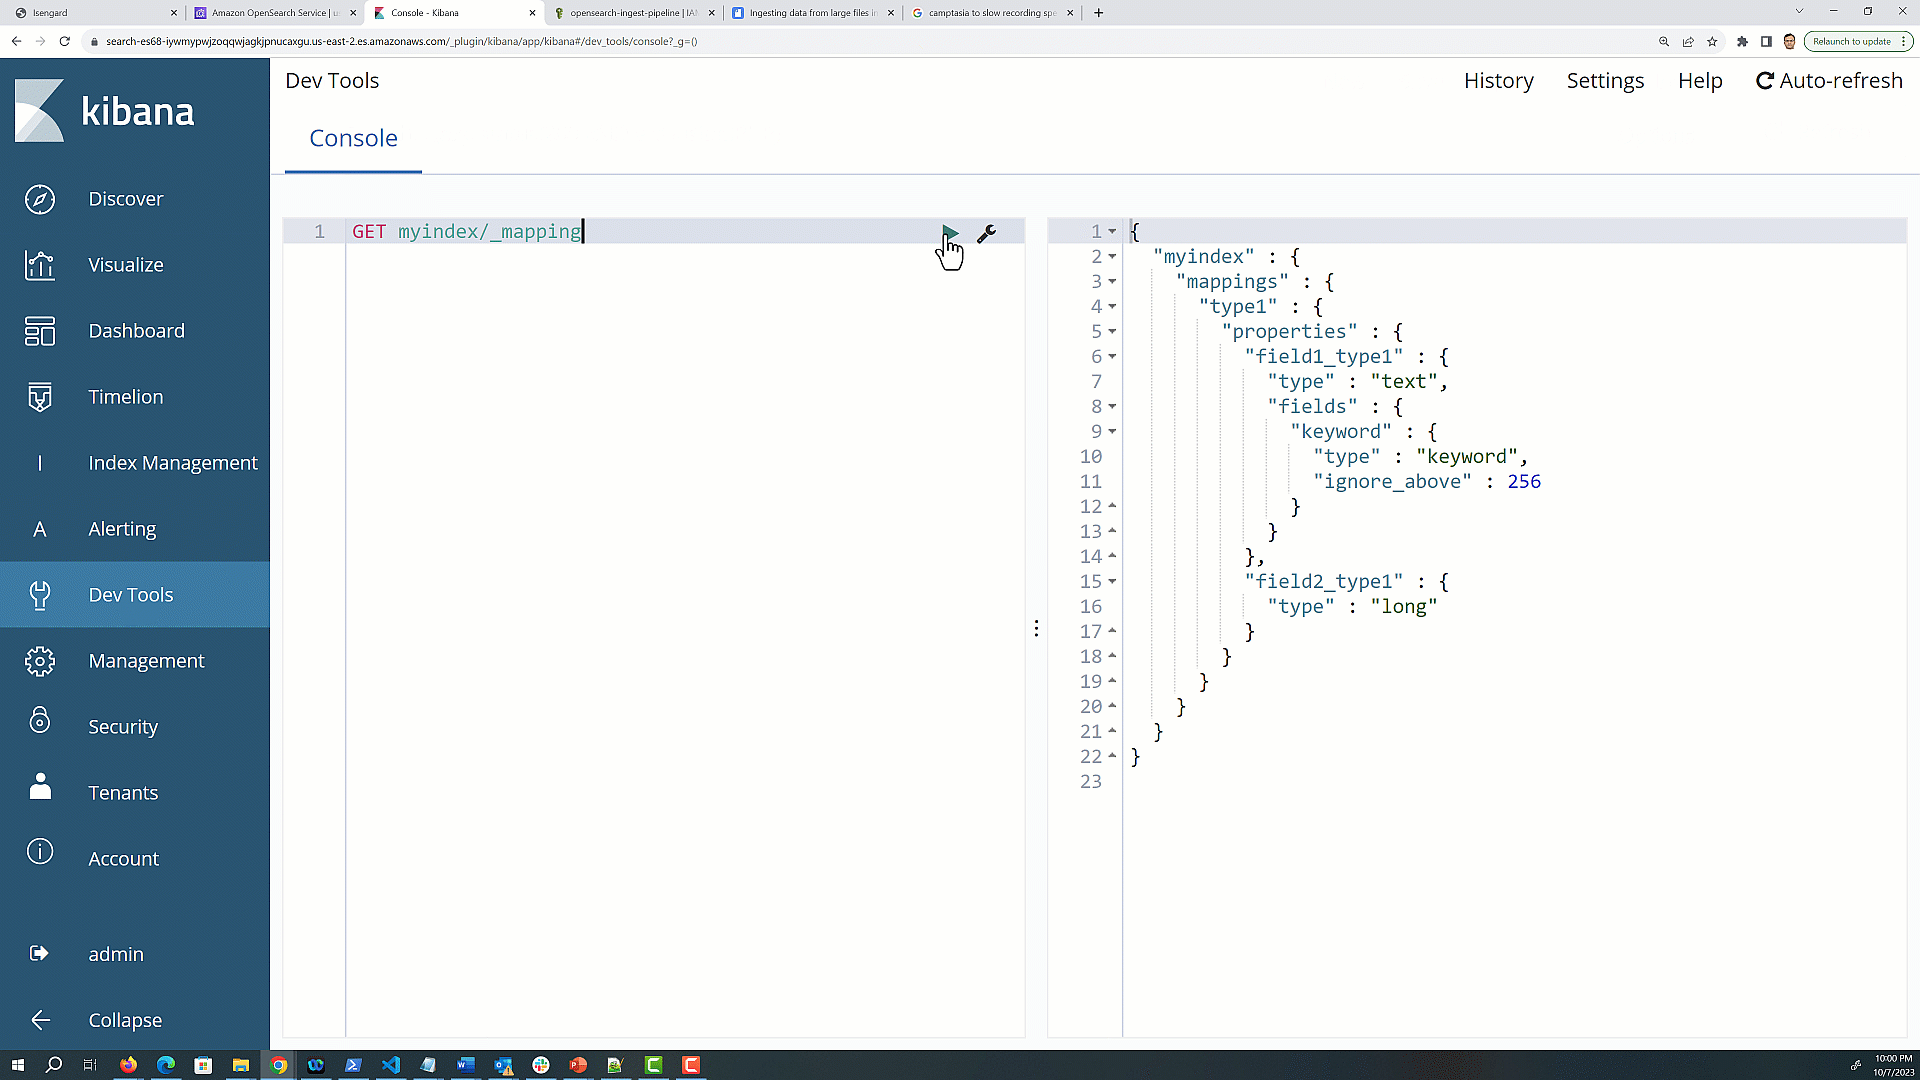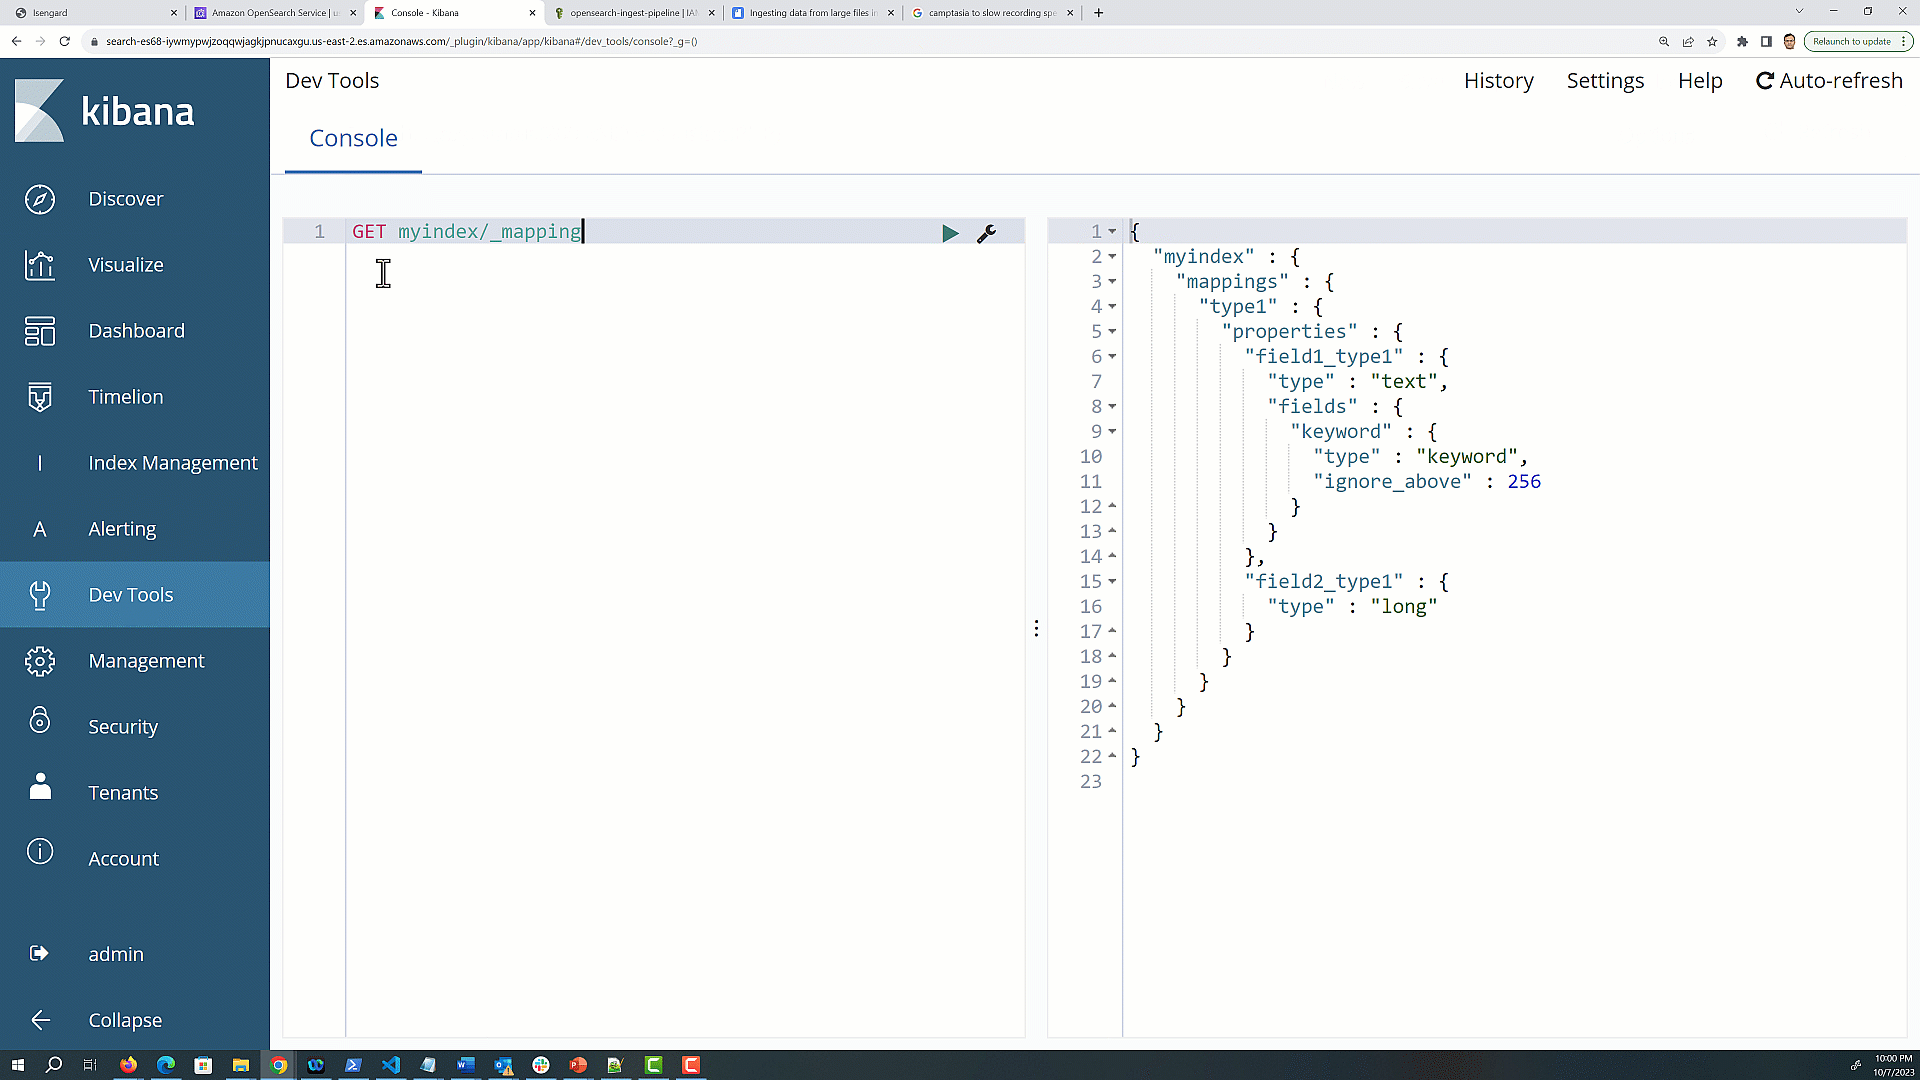
  1. Navigate to dev tools and use the following GET <index> mapping API to fetch the mapping information for all the indexes:
GET /index-name/_mapping

The mapping response will contain a JSON structure that represents the mapping for your index.

  1. Look for the top-level keys in the response JSON; each key represents a custom type within the index.

The _doc type is used for the default type in Elasticsearch 7.x and OpenSearch Service 1.x, but you may see additional types that you defined in earlier versions of Elasticsearch. The following is an example response for an index with two custom types, type1 and type2.

Note that indexes created in 5.x will continue to function in 6.x as they did in 5.x, but indexes created in 6.x only allow a single type per index.

{
  "myindex": {
    "mappings": {
      "type1": {
        "properties": {
          "field1_type1": {
            "type": "text"
          },
          "field2_type1": {
            "type": "integer"
          }
        }
      },
      "type2": {
        "properties": {
          "field1_type2": {
            "type": "keyword"
          },
          "field2_type2": {
            "type": "date"
          }
        }
      }
    }
  }
}

To fix the multiple mapping types in your existing domain, you need to reindex the data, where you can create one index for each mapping. This is a crucial step in the migration process because OpenSearch doesn’t support multiple types within a single index. In the next steps, we convert an index that has multiple mapping types into two separate indexes, each using the _doc type.

  1. You can unify the mapping by using your existing index name as a root and adding the type as a suffix. For example, the following code creates two indexes with myindex as the root name and type1 and type2 as the suffix:
    # Create an index for "type1"
    PUT /myindex_type1
    
    # Create an index for "type2"
    PUT /myindex_type2

  2. Use the _reindex API to reindex the data from the original index into the two new indexes. Alternately, you can reload the data from its source, if you’re keeping it in another system.
    POST _reindex
    {
      "source": {
        "index": "myindex",
        "type": "type1"  
      },
      "dest": {
        "index": "myindex_type1",
        "type": "_doc"  
      }
    }
    POST _reindex
    {
      "source": {
        "index": "myindex",
        "type": "type2"  
      },
      "dest": {
        "index": "myindex_type2",
        "type": "_doc"  
      }
    }

  3. If your application was previously querying the original index with multiple types, you’ll need to update your queries to specify the new indexes with _doc as the type. For example, if your client was querying using myindex, which has been reindexed to myindex_type1 and myindex_type2, then change your clients to point to myindex*, which will query across both indexes.
  4. After you have verified that the data is successfully reindexed and your application is working as expected with the new indexes, you should delete the original index before starting the upgrade, because it won’t be supported in the new version. Be cautious when deleting data and make sure you have backups if necessary.
  5. As part of this upgrade, Kibana will be replaced with OpenSearch Dashboards. When you’re done with the upgrade in the next step, you should advocate your users to use the new endpoint, which will be _dashboards. If you use a custom endpoint, be sure to update it to point to /_dashboards.
  6. We recommend that you update your AWS Identity and Access Management (IAM) policies to use the renamed API operations. However, OpenSearch Service will continue to respect existing policies by internally replicating the old API permissions. Service control policies (SCPs) introduce an additional layer of complexity compared to standard IAM. To prevent your SCP policies from breaking, you need to add both the old and the new API operations to each of your SCP policies.

Start the upgrade

The upgrade process is irreversible and can’t be paused or cancelled. You should make sure that everything will go smoothly by running a proof of concept (POC) check. By building a POC, you ensure data preservation, avoid compatibility issues, prevent unwanted bugs, and mitigate risks. You can run a POC with a small domain on the new version, and with a small subset of your data. Deploy and run any front-end code that communicates with OpenSearch Service via API against your test domain. Use your ingest pipeline to send data to your test domain as well, ensuring nothing breaks. Import or rebuild dashboards, alerts, anomaly detectors, and so on. This simple precaution can make your upgrade experience smoother and trouble-free while minimizing potential disruptions.

When OpenSearch Service starts the upgrade, it can take from 15 minutes to several hours to complete. OpenSearch Dashboards might be unavailable during some or all of the duration of the upgrade.

In this section, we show how you can start an upgrade using the AWS Management Console. You can also run the upgrade using the AWS Command Line Interface (AWS CLI) or AWS SDK. For more information, refer to Starting an upgrade (CLI) and Starting an upgrade (SDK).

  1. Take a manual snapshot of your domain.

This snapshot serves as a backup that you can restore on a new domain if you want to return to using the prior version.

  1. On the OpenSearch Service console, choose the domain that you want to upgrade.
  2. On the Actions menu, choose Upgrade.
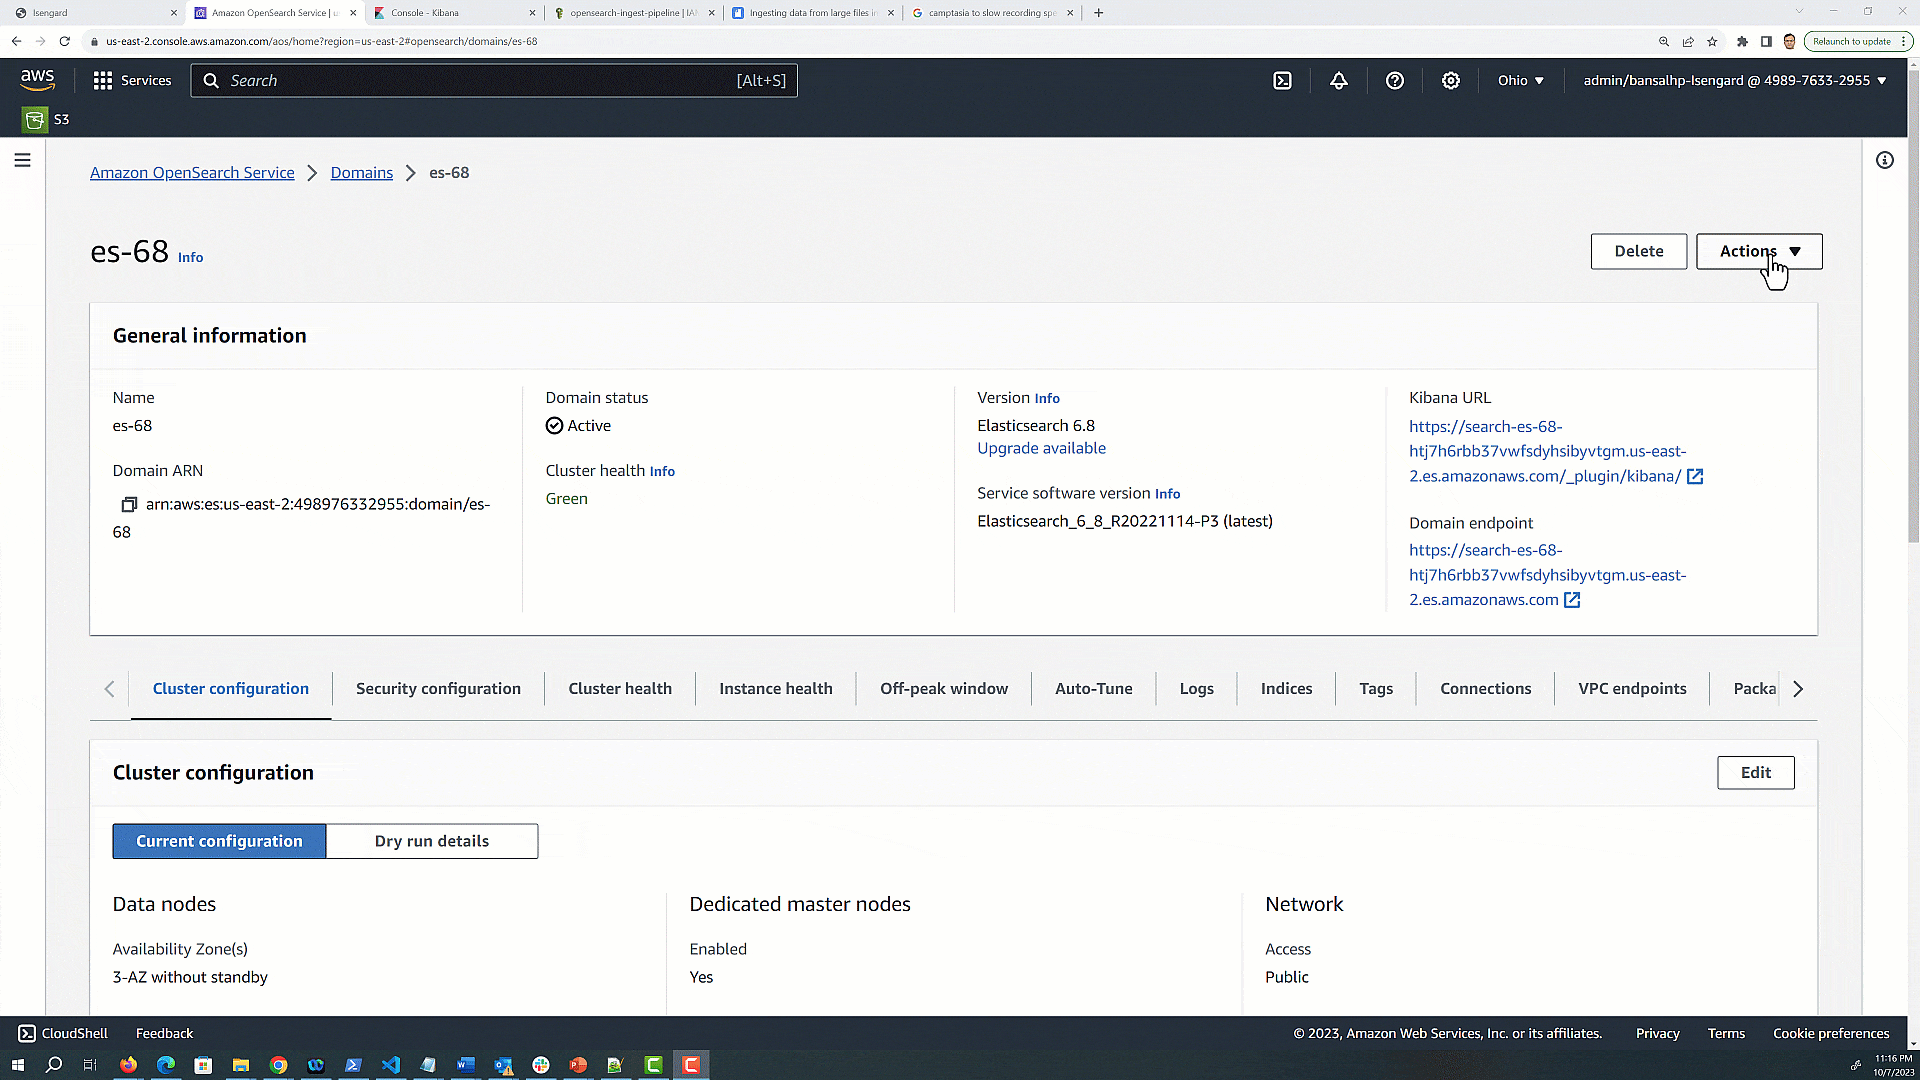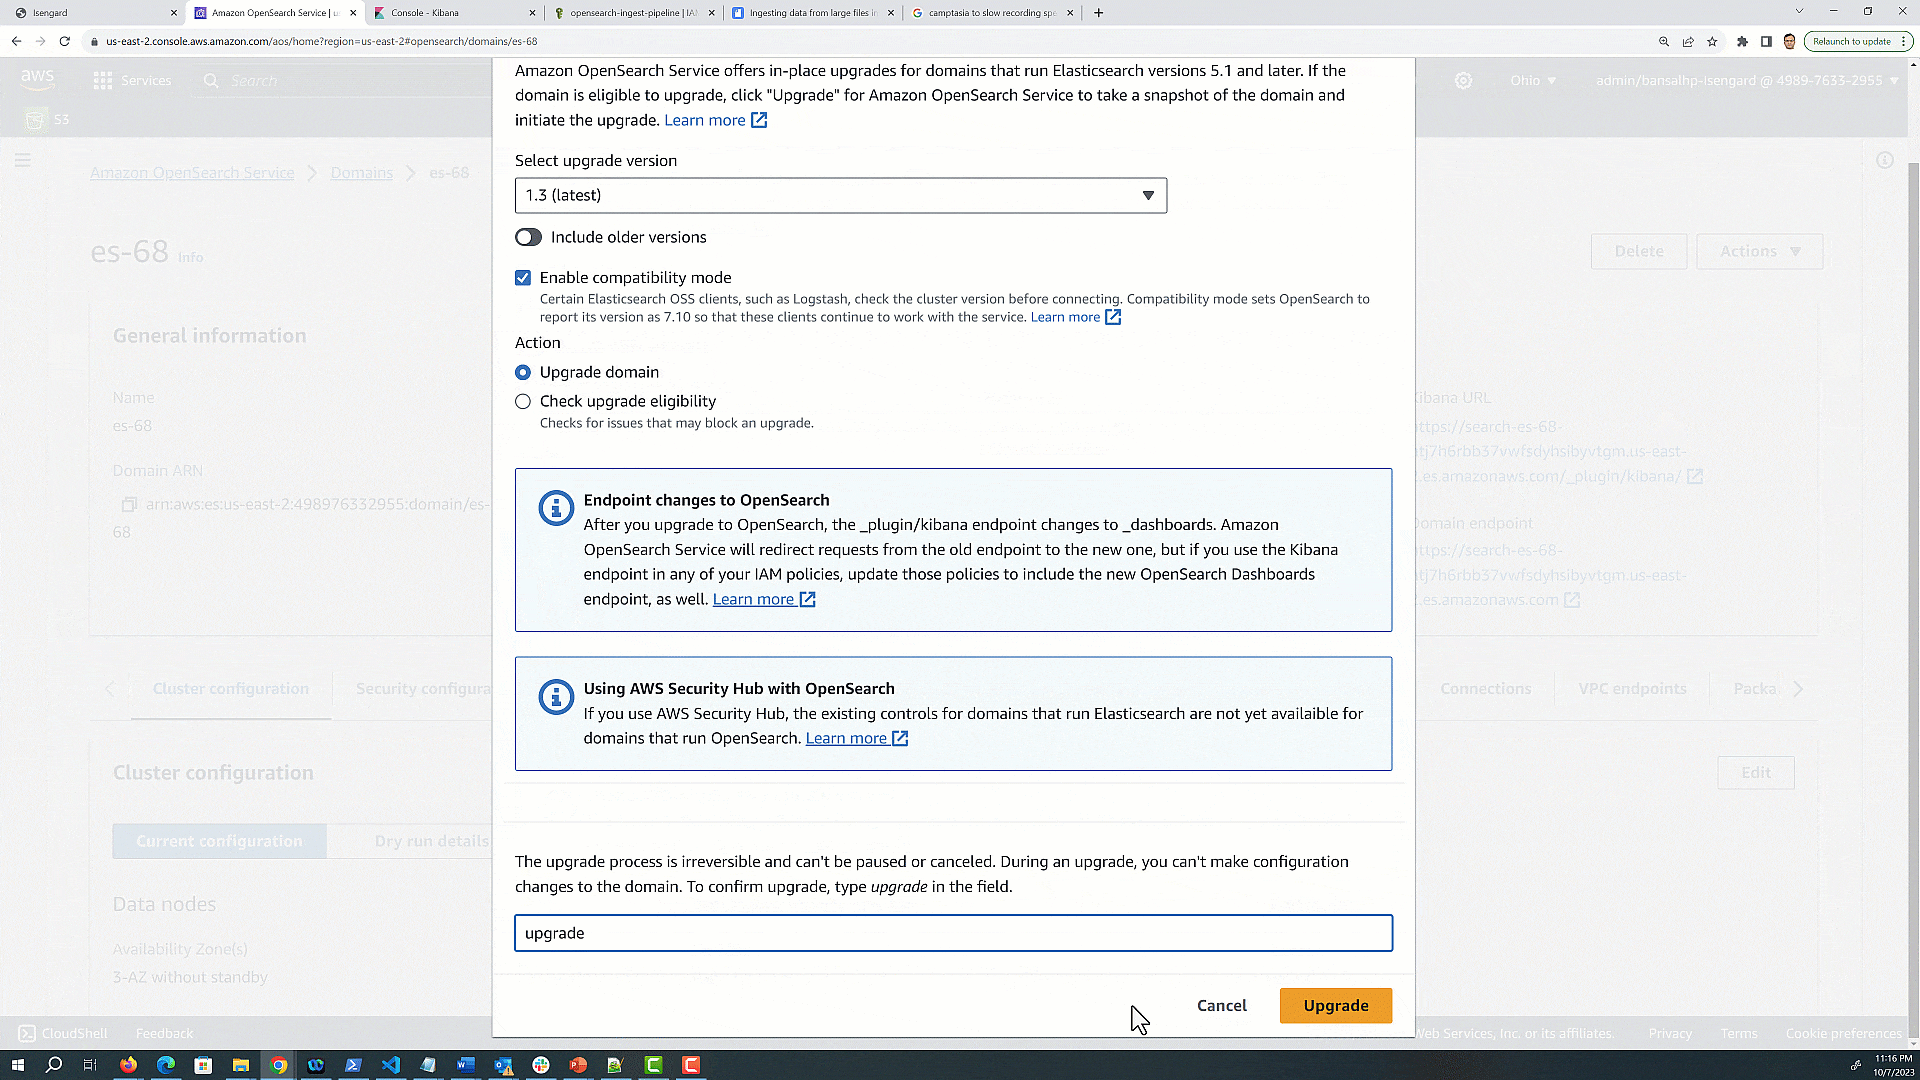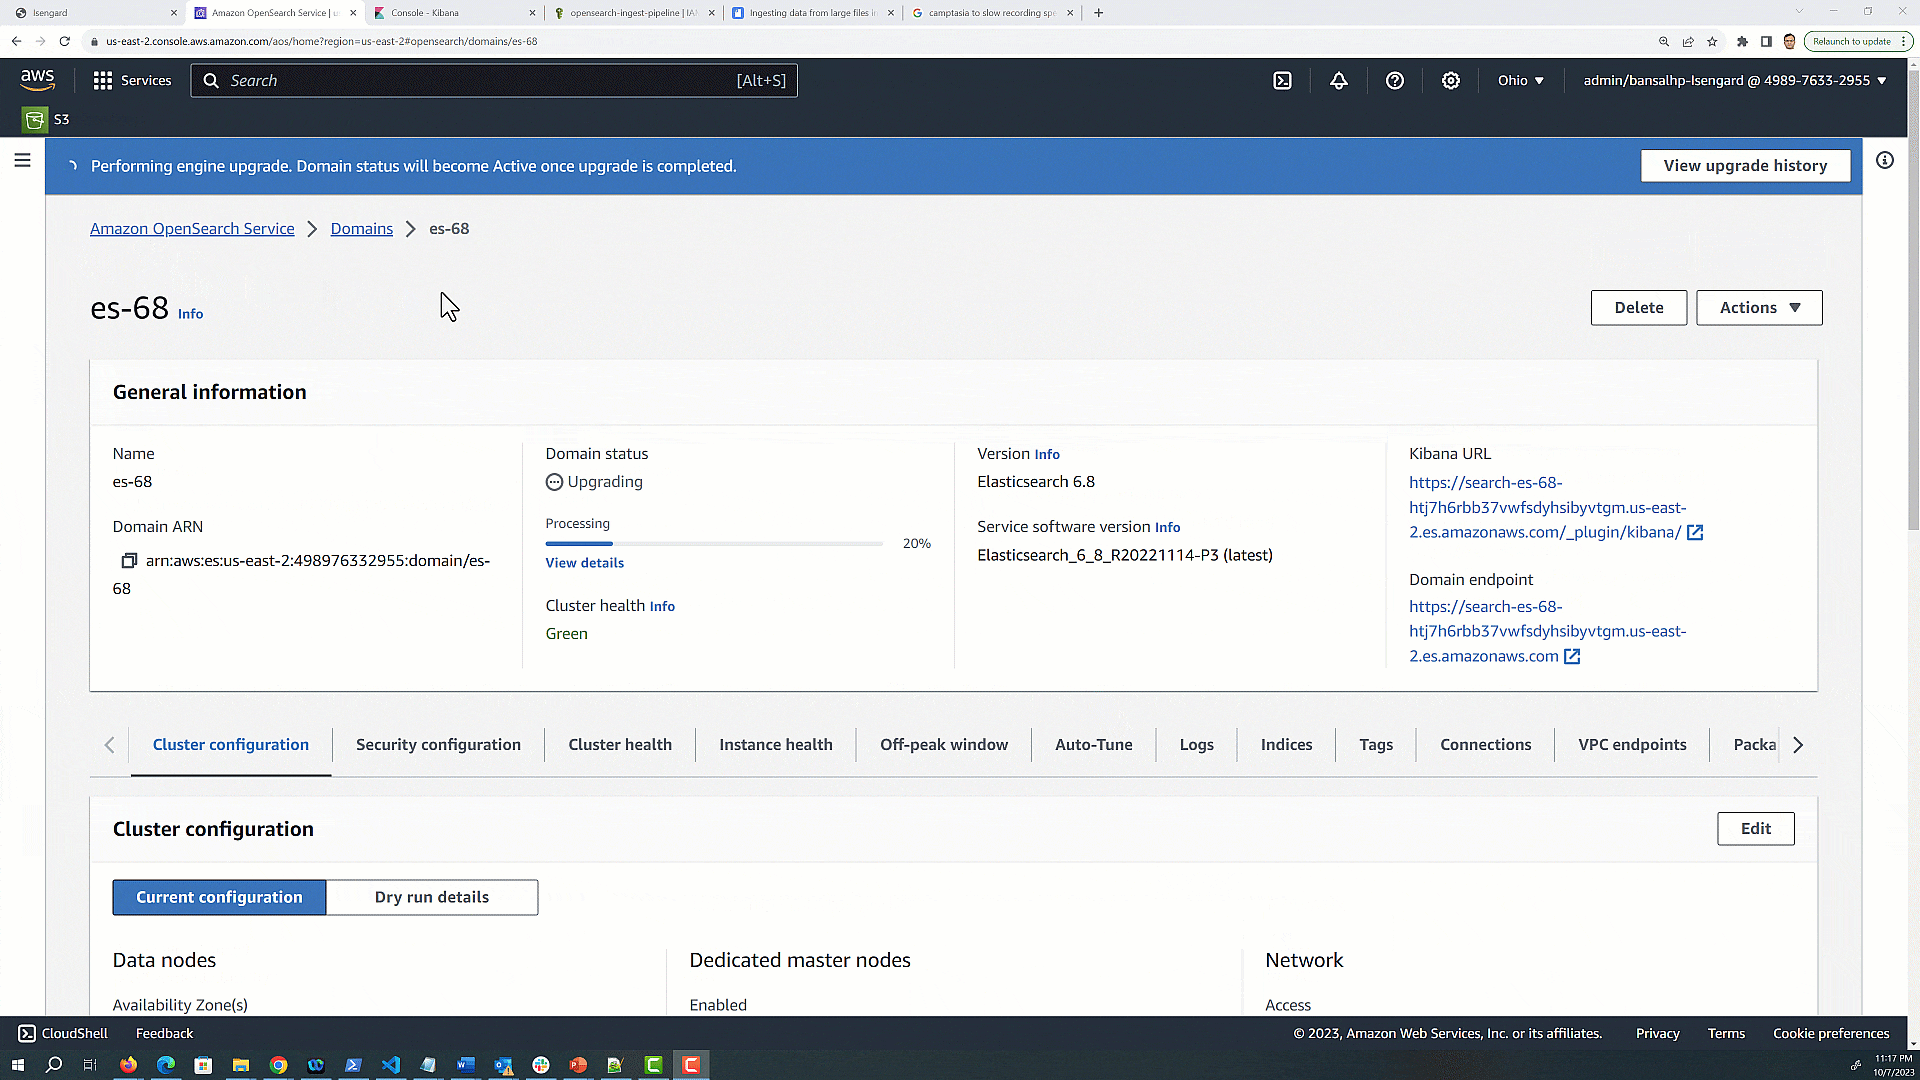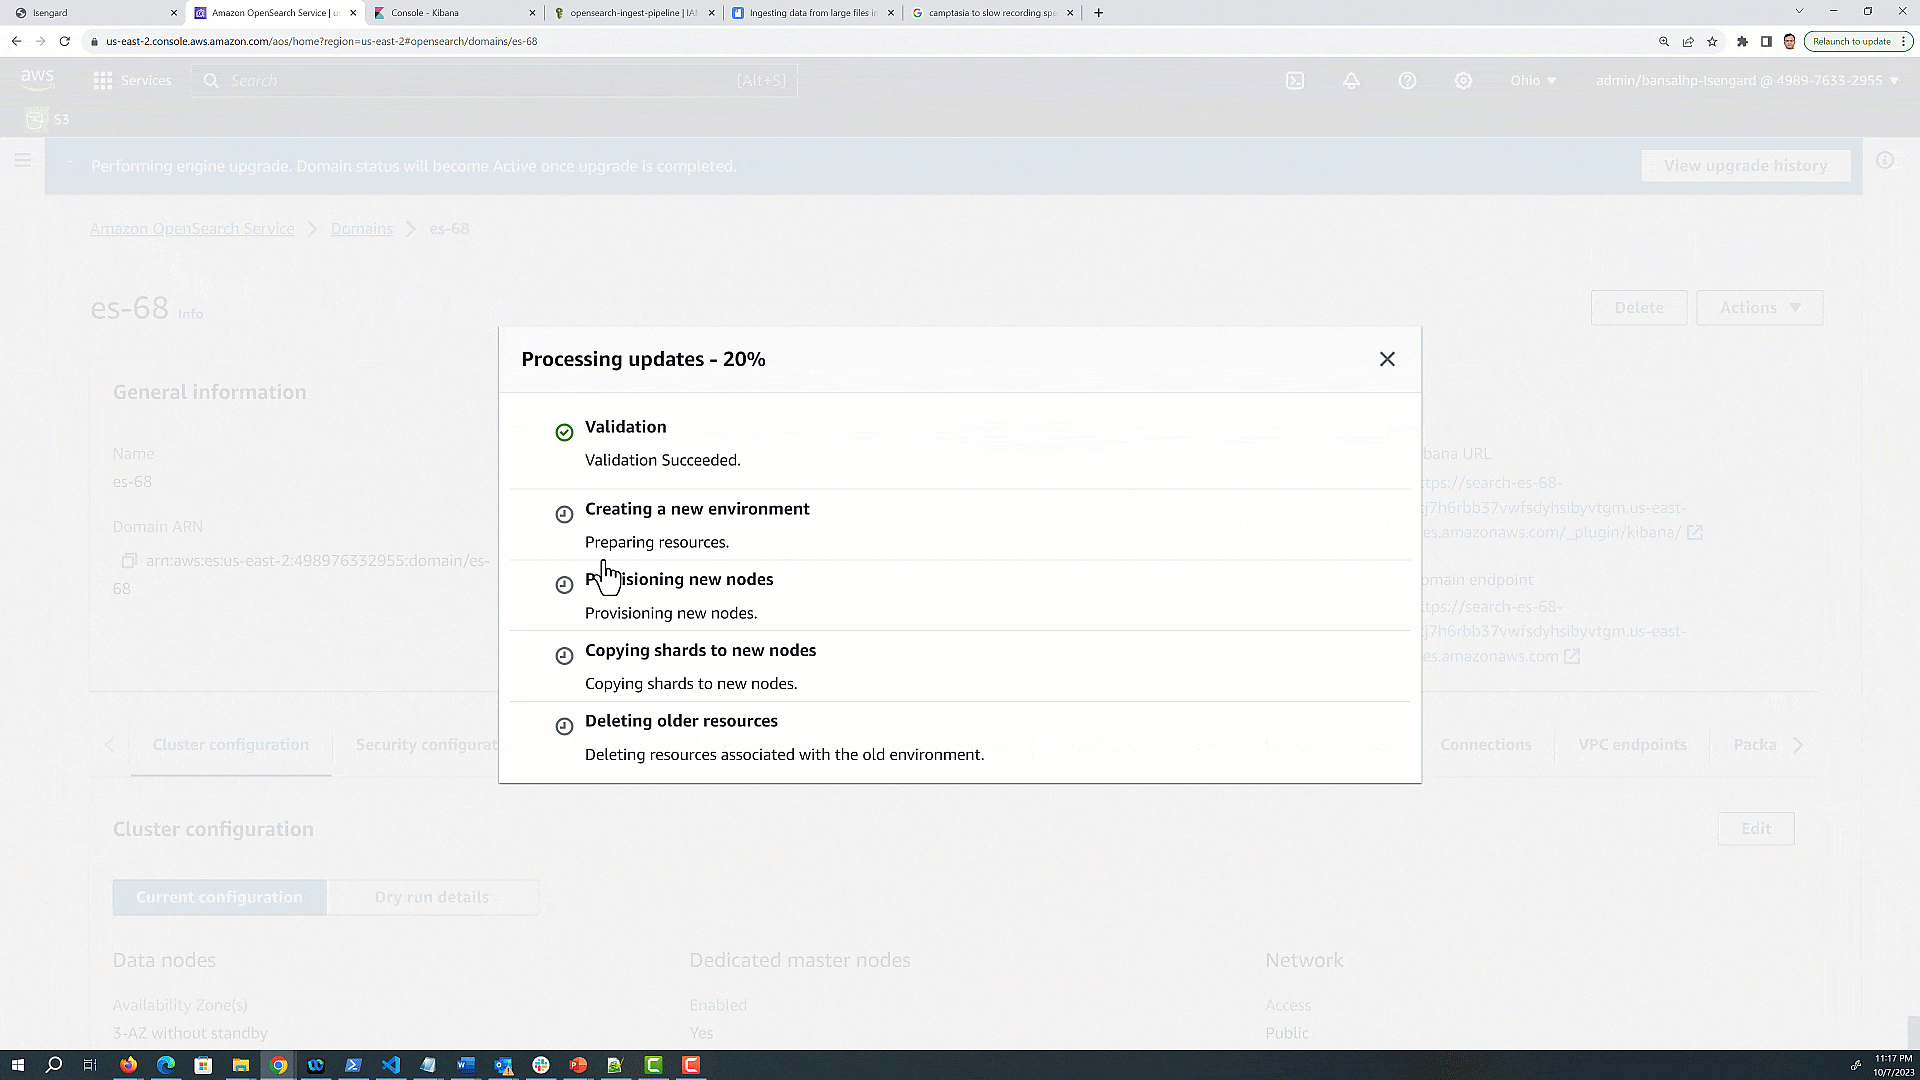
  3. Select the target version as OpenSearch 1.3. If you’re upgrading to an OpenSearch version, then you’ll be able to enable compatibility mode. If you enable this setting, OpenSearch reports its version as 7.10 to allow Elastic’s open-source clients and plugins like Logstash to continue working with your OpenSearch Service domain.
  4. Choose Check Upgrade Eligibility, which helps you identify if there are any breaking changes you still need to fix before running an upgrade.
  5. Choose Upgrade.
  6. Check the status on the domain dashboard to monitor the status of the upgrade.

The following graphic gives a quick demonstration of running and monitoring the upgrade via the preceding steps.

Post-upgrade changes and validations

Now that you have successfully upgraded your domain to OpenSearch Service 1.3, be sure to make the following changes:

  • Custom endpoint – A custom endpoint for your OpenSearch Service domain makes it straightforward for you to refer to your OpenSearch and OpenSearch Dashboards URLs. You can include your company’s branding or just use a shorter, easier-to-remember endpoint than the standard one. In OpenSearch Service, Kibana has been renamed to dashboards. After you upgrade a domain from the Elasticsearch engine to the OpenSearch engine, the /_plugin/kibana endpoint changes to /_dashboards. If you use the Kibana endpoint to set up a custom domain, you need to update it to include the new /_dashboards endpoint.
  • SAML authentication for OpenSearch Dashboards – After you upgrade your domain to OpenSearch Service, you need to change all Kibana URLs configured in your identity provider (IdP) from /_plugin/kibana to /_dashboards. The most common URLs are assertion consumer service (ACS) URLs and recipient URLs.

Conclusion

This post discussed what to consider when planning to upgrade your existing Elasticsearch engine in your OpenSearch Service domain to the OpenSearch engine. OpenSearch Service continues to support older engine versions, including open-source versions of Elasticsearch from 1.x through 7.10. By migrating forward to OpenSearch Service, you will be able to take advantage of bug fixes, performance improvements, new service features, and expanded instance types for your data nodes, like AWS Graviton 2 instances.

If you have feedback about this post, share it in the comments section. If you have questions about this post, start a new thread on the Amazon OpenSearch Service forum or contact AWS Support.


About the Authors

Prashant Agrawal is a Sr. Search Specialist Solutions Architect with Amazon OpenSearch Service. He works closely with customers to help them migrate their workloads to the cloud and helps existing customers fine-tune their clusters to achieve better performance and save on cost. Before joining AWS, he helped various customers use OpenSearch and Elasticsearch for their search and log analytics use cases. When not working, you can find him traveling and exploring new places. In short, he likes doing Eat → Travel → Repeat.

Harsh Bansal is a Solutions Architect at AWS with Analytics as his area of specialty.He has been building solutions to help organizations make data-driven decisions.

Mask and redact sensitive data published to Amazon SNS using managed and custom data identifiers

Post Syndicated from Otavio Ferreira original https://aws.amazon.com/blogs/security/mask-and-redact-sensitive-data-published-to-amazon-sns-using-managed-and-custom-data-identifiers/

Today, we’re announcing a new capability for Amazon Simple Notification Service (Amazon SNS) message data protection. In this post, we show you how you can use this new capability to create custom data identifiers to detect and protect domain-specific sensitive data, such as your company’s employee IDs. Previously, you could only use managed data identifiers to detect and protect common sensitive data, such as names, addresses, and credit card numbers.

Overview

Amazon SNS is a serverless messaging service that provides topics for push-based, many-to-many messaging for decoupling distributed systems, microservices, and event-driven serverless applications. As applications become more complex, it can become challenging for topic owners to manage the data flowing through their topics. These applications might inadvertently start sending sensitive data to topics, increasing regulatory risk. To mitigate the risk, you can use message data protection to protect sensitive application data using built-in, no-code, scalable capabilities.

To discover and protect data flowing through SNS topics with message data protection, you can associate data protection policies to your topics. Within these policies, you can write statements that define which types of sensitive data you want to discover and protect. Within each policy statement, you can then define whether you want to act on data flowing inbound to an SNS topic or outbound to an SNS subscription, the AWS accounts or specific AWS Identity and Access Management (IAM) principals the statement applies to, and the actions you want to take on the sensitive data found.

Now, message data protection provides three actions to help you protect your data. First, the audit operation reports on the amount of sensitive data found. Second, the deny operation helps prevent the publishing or delivery of payloads that contain sensitive data. Third, the de-identify operation can mask or redact the sensitive data detected. These no-code operations can help you adhere to a variety of compliance regulations, such as Health Insurance Portability and Accountability Act (HIPAA), Federal Risk and Authorization Management Program (FedRAMP), General Data Protection Regulation (GDPR), and Payment Card Industry Data Security Standard (PCI DSS).

This message data protection feature coexists with the message data encryption feature in SNS, both contributing to an enhanced security posture of your messaging workloads.

Managed and custom data identifiers

After you add a data protection policy to your SNS topic, message data protection uses pattern matching and machine learning models to scan your messages for sensitive data, then enforces the data protection policy in real time. The types of sensitive data are referred to as data identifiers. These data identifiers can be either managed by Amazon Web Services (AWS) or custom to your domain.

Managed data identifiers (MDI) are organized into five categories:

In a data protection policy statement, you refer to a managed data identifier using its Amazon Resource Name (ARN), as follows:

{
    "Name": "__example_data_protection_policy",
    "Description": "This policy protects sensitive data in expense reports",
    "Version": "2021-06-01",
    "Statement": [{
        "DataIdentifier": [
            "arn:aws:dataprotection::aws:data-identifier/CreditCardNumber"
        ],
        "..."
    }]
}

Custom data identifiers (CDI), on the other hand, enable you to define custom regular expressions in the data protection policy itself, then refer to them from policy statements. Using custom data identifiers, you can scan for business-specific sensitive data, which managed data identifiers can’t. For example, you can use a custom data identifier to look for company-specific employee IDs in SNS message payloads. Internally, SNS has guardrails to make sure custom data identifiers are safe and that they add only low single-digit millisecond latency to message processing.

In a data protection policy statement, you refer to a custom data identifier using only the name that you have given it, as follows:

{
    "Name": "__example_data_protection_policy",
    "Description": "This policy protects sensitive data in expense reports",
    "Version": "2021-06-01",
    "Configuration": {
        "CustomDataIdentifier": [{
            "Name": "MyCompanyEmployeeId", "Regex": "EID-\d{9}-US"
        }]
    },
    "Statement": [{
        "DataIdentifier": [
            "arn:aws:dataprotection::aws:data-identifier/CreditCardNumber",
            "MyCompanyEmployeeId"
        ],
        "..."
    }]
}

Note that custom data identifiers can be used in conjunction with managed data identifiers, as part of the same data protection policy statement. In the preceding example, both MyCompanyEmployeeId and CreditCardNumber are in scope.

For more information, see Data Identifiers, in the SNS Developer Guide.

Inbound and outbound data directions

In addition to the DataIdentifier property, each policy statement also sets the DataDirection property (whose value can be either Inbound or Outbound) as well as the Principal property (whose value can be any combination of AWS accounts, IAM users, and IAM roles).

When you use message data protection for data de-identification and set DataDirection to Inbound, instances of DataIdentifier published by the Principal are masked or redacted before the payload is ingested into the SNS topic. This means that every endpoint subscribed to the topic receives the same modified payload.

When you set DataDirection to Outbound, on the other hand, the payload is ingested into the SNS topic as-is. Then, instances of DataIdentifier are either masked, redacted, or kept as-is for each subscribing Principal in isolation. This means that each endpoint subscribed to the SNS topic might receive a different payload from the topic, with different sensitive data de-identified, according to the data access permissions of its Principal.

The following snippet expands the example data protection policy to include the DataDirection and Principal properties.

{
    "Name": "__example_data_protection_policy",
    "Description": "This policy protects sensitive data in expense reports",
    "Version": "2021-06-01",
    "Configuration": {
        "CustomDataIdentifier": [{
            "Name": "MyCompanyEmployeeId", "Regex": "EID-\d{9}-US"
        }]
    },
    "Statement": [{
        "DataIdentifier": [
            "MyCompanyEmployeeId",
            "arn:aws:dataprotection::aws:data-identifier/CreditCardNumber"
        ],
        "DataDirection": "Outbound",
        "Principal": [ "arn:aws:iam::123456789012:role/ReportingApplicationRole" ],
        "..."
    }]
}

In this example, ReportingApplicationRole is the authenticated IAM principal that called the SNS Subscribe API at subscription creation time. For more information, see How do I determine the IAM principals for my data protection policy? in the SNS Developer Guide.

Operations for data de-identification

To complete the policy statement, you need to set the Operation property, which informs the SNS topic of the action that it should take when it finds instances of DataIdentifer in the outbound payload.

The following snippet expands the data protection policy to include the Operation property, in this case using the Deidentify object, which in turn supports masking and redaction.

{
    "Name": "__example_data_protection_policy",
    "Description": "This policy protects sensitive data in expense reports",
    "Version": "2021-06-01",
    "Configuration": {
        "CustomDataIdentifier": [{
            "Name": "MyCompanyEmployeeId", "Regex": "EID-\d{9}-US"
        }]
    },
    "Statement": [{
        "Principal": [
            "arn:aws:iam::123456789012:role/ReportingApplicationRole"
        ],
        "DataDirection": "Outbound",
        "DataIdentifier": [
            "MyCompanyEmployeeId",
            "arn:aws:dataprotection::aws:data-identifier/CreditCardNumber"
        ],
        "Operation": { "Deidentify": { "MaskConfig": { "MaskWithCharacter": "#" } } }
    }]
}

In this example, the MaskConfig object instructs the SNS topic to mask instances of CreditCardNumber in Outbound messages to subscriptions created by ReportingApplicationRole, using the MaskWithCharacter value, which in this case is the hash symbol (#). Alternatively, you could have used the RedactConfig object instead, which would have instructed the SNS topic to simply cut the sensitive data off the payload.

The following snippet shows how the outbound payload is masked, in real time, by the SNS topic.

// original message published to the topic:
My credit card number is 4539894458086459

// masked message delivered to subscriptions created by ReportingApplicationRole:
My credit card number is ################

For more information, see Data Protection Policy Operations, in the SNS Developer Guide.

Applying data de-identification in a use case

Consider a company where managers use an internal expense report management application where expense reports from employees can be reviewed and approved. Initially, this application depended only on an internal payment application, which in turn connected to an external payment gateway. However, this workload eventually became more complex, because the company started also paying expense reports filed by external contractors. At that point, the company built a mobile application that external contractors could use to view their approved expense reports. An important business requirement for this mobile application was that specific financial and PII data needed to be de-identified in the externally displayed expense reports. Specifically, both the credit card number used for the payment and the internal employee ID that approved the payment had to be masked.

Figure 1: Expense report processing application

Figure 1: Expense report processing application

To distribute the approved expense reports to both the payment application and the reporting application that backed the mobile application, the company used an SNS topic with a data protection policy. The policy has only one statement, which masks credit card numbers and employee IDs found in the payload. This statement applies only to the IAM role that the company used for subscribing the AWS Lambda function of the reporting application to the SNS topic. This access permission configuration enabled the Lambda function from the payment application to continue receiving the raw data from the SNS topic.

The data protection policy from the previous section addresses this use case. Thus, when a message representing an expense report is published to the SNS topic, the Lambda function in the payment application receives the message as-is, whereas the Lambda function in the reporting application receives the message with the financial and PII data masked.

Deploying the resources

You can apply a data protection policy to an SNS topic using the AWS Management Console, AWS Command Line Interface (AWS CLI), AWS SDK, or AWS CloudFormation.

To automate the provisioning of the resources and the data protection policy of the example expense management use case, we’re going to use CloudFormation templates. You have two options for deploying the resources:

Deploy using the individual CloudFormation templates in sequence

  1. Prerequisites template: This first template provisions two IAM roles with a managed policy that enables them to create SNS subscriptions and configure the subscriber Lambda functions. You will use these provisioned IAM roles in steps 3 and 4 that follow.
  2. Topic owner template: The second template provisions the SNS topic along with its access policy and data protection policy.
  3. Payment subscriber template: The third template provisions the Lambda function and the corresponding SNS subscription that comprise of the Payment application stack. When prompted, select the PaymentApplicationRole in the Permissions panel before running the template. Moreover, the CloudFormation console will require you to acknowledge that a CloudFormation transform might require access capabilities.
  4. Reporting subscriber template: The final template provisions the Lambda function and the SNS subscription that comprise of the Reporting application stack. When prompted, select the ReportingApplicationRole in the Permissions panel, before running the template. Moreover, the CloudFormation console will require, once again, that you acknowledge that a CloudFormation transform might require access capabilities.
Figure 2: Select IAM role

Figure 2: Select IAM role

Now that the application stacks have been deployed, you’re ready to start testing.

Testing the data de-identification operation

Use the following steps to test the example expense management use case.

  1. In the Amazon SNS console, select the ApprovalTopic, then choose to publish a message to it.
  2. In the SNS message body field, enter the following message payload, representing an external contractor expense report, then choose to publish this message:
    {
        "expense": {
            "currency": "USD",
            "amount": 175.99,
            "category": "Office Supplies",
            "status": "Approved",
            "created_at": "2023-10-17T20:03:44+0000",
            "updated_at": "2023-10-19T14:21:51+0000"
        },
        "payment": {
            "credit_card_network": "Visa",
            "credit_card_number": "4539894458086459"
        },
        "reviewer": {
            "employee_id": "EID-123456789-US",
            "employee_location": "Seattle, USA"
        },
        "contractor": {
            "employee_id": "CID-000012348-CA",
            "employee_location": "Vancouver, CAN"
        }
    }
    

  3. In the CloudWatch console, select the log group for the PaymentLambdaFunction, then choose to view its latest log stream. Now look for the log stream entry that shows the message payload received by the Lambda function. You will see that no data has been masked in this payload, as the payment application requires raw financial data to process the credit card transaction.
  4. Still in the CloudWatch console, select the log group for the ReportingLambdaFunction, then choose to view its latest log stream. Now look for the log stream entry that shows the message payload received by this Lambda function. You will see that the values for properties credit_card_number and employee_id have been masked, protecting the financial data from leaking into the external reporting application.
    {
        "expense": {
            "currency": "USD",
            "amount": 175.99,
            "category": "Office Supplies",
            "status": "Approved",
            "created_at": "2023-10-17T20:03:44+0000",
            "updated_at": "2023-10-19T14:21:51+0000"
        },
        "payment": {
            "credit_card_network": "Visa",
            "credit_card_number": "################"
        },
        "reviewer": {
            "employee_id": "################",
            "employee_location": "Seattle, USA"
        },
        "contractor": {
            "employee_id": "CID-000012348-CA",
            "employee_location": "Vancouver, CAN"
        }
    }
    

As shown, different subscribers received different versions of the message payload, according to their sensitive data access permissions.

Cleaning up the resources

After testing, avoid incurring usage charges by deleting the resources that you created. Open the CloudFormation console and delete the four CloudFormation stacks that you created during the walkthrough.

Conclusion

This post showed how you can use Amazon SNS message data protection to discover and protect sensitive data published to or delivered from your SNS topics. The example use case shows how to create a data protection policy that masks messages delivered to specific subscribers if the payloads contain financial or personally identifiable information.

For more details, see message data protection in the SNS Developer Guide. For information on costs, see SNS pricing.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on AWS re:Post or contact AWS Support.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.

Otavio-Ferreira-author

Otavio Ferreira

Otavio is the GM for Amazon SNS, and has been leading the service since 2016, responsible for software engineering, product management, technical program management, and technical operations. Otavio has spoken at AWS conferences—AWS re:Invent and AWS Summit—and written a number of articles for the AWS Compute and AWS Security blogs.

IAM Roles Anywhere with an external certificate authority

Post Syndicated from Cody Penta original https://aws.amazon.com/blogs/security/iam-roles-anywhere-with-an-external-certificate-authority/

AWS Identity and Access Management Roles Anywhere allows you to use temporary Amazon Web Services (AWS) credentials outside of AWS by using X.509 Certificates issued by your certificate authority (CA). Faraz Angabini goes deep into using IAM Roles Anywhere in his blog post Extend AWS IAM roles to workloads outside of AWS with IAM Roles Anywhere. In this blog post, I take a step back from his post and first define what public key infrastructure (PKI) is and help you set one up for use for IAM Roles Anywhere.

I focus on setting up local PKI for testing purposes by building a basic, minimal certificate authority using openssl. I chose openssl as it’s a standard industry tool for cryptography and is often installed by default on many operating systems. However, you can achieve similar results in a simpler manner using open source tools such as cfssl. In this blog post, we create a local PKI for non-production use cases only for the sake of brevity and to focus more on understanding the core fundamentals. As I go along, I’ll point out what I left out and where to find more information.

Overview

The overall flow of this blog is as follows, there’s some new terminology, so please use this as a map to refer to as you read along to understand the flow. If you’re taking cornell notes, now would be the right time to write key words you see below such as key, certificate, end-entity certificate, certificate authority, CA, trust, IAM Roles Anywhere, and others that pop out to you.

  1. Explain the concepts of keys and certificates and their uses.
  2. Using what you learn about keys and certificates, create a CA.
  3. Import your certificate authority into IAM Roles Anywhere and establish trust between your certificate authority and IAM Roles Anywhere.
  4. Create an end-entity certificate.
  5. Exchange your end-entity certificate for IAM credentials using IAM Roles Anywhere.

Background

IAM Roles Anywhere is compatible with existing PKIs, and for demonstration purposes, you’ll create local infrastructure using openssl to get a deep understanding of the terminology and concepts. Existing PKIs such as AWS Certificate Manager (ACM) and third-party certificate authority services often abstract and simplify this process. With that being said, you have to start somewhere, so let’s start with a key.

What exactly is a key? The National Institute of Standards and Technology (NIST) defines a key as “a parameter used in conjunction with a cryptographic algorithm that determines the specific operation of that algorithm,” which is a formal way of saying for anything you would put inside the key parameter in a function like encrypt(key, data), decrypt(key, data), or sign(key, data). The definition cleverly avoids defining the key by its structure—such as, “It’s a sequence of 256 truly random bits” — as that’s not always the case. For example, in asymmetric encryption you have two keys. One key is private and should not, under any circumstances, be shared outside of your control; while another key is public and can be safely shared with the outside world. To illustrate this, let’s look at actual commands to generate keys:

openssl genpkey -out private.key \
    -algorithm RSA \
    -pkeyopt rsa_keygen_bits:2048 # 2048 minimum key size for RSA, later we use 4096

NOTE: The key is printed in PKCS#8 format, which is a file format for the private key along with some metadata

You can inspect this key with:

cat private.key
-----BEGIN PRIVATE KEY-----
MIIEvgIBADANBgkqhkiG9w0BAQEFAASCBKgwggSkAgEAAoIBAQC/BWpcJqlVDJkC
wr+qrwEgNPSpXM2iSQQAfjS81pll4I5yp//7lm1UqKeBTbaYp9rVec1uzKQrw3xt
...36 lines removed for brevity
mx2sovZyFB7Xe4/99TGLQuHTtgLYYVEN/iFtvsbjPjR7X+R76GWPLdUFdRes0gPo
dlsfnsVKVkUUJKZy0Y2nOrwb2gNSUd/NjcgV9XHEW4y+Sclk/EkdAML1d3aGM0VQ
AaLL8xb75To0VqSQPW12URJM
-----END PRIVATE KEY-----

The public key is embedded inside the private key and you can even pull the public part from the private key.

openssl pkey -in private.key -pubout -out public.key

And like the private key, you can inspect it:

cat public.key
-----BEGIN PUBLIC KEY-----
MIIBIjANBgkqhkiG9w0BAQEFAAOCAQ8AMIIBCgKCAQEAvwVqXCapVQyZAsK/qq8B
IDT0qVzNokkEAH40vNaZZeCOcqf/+5ZtVKingU22mKfa1XnNbsykK8N8bSY9J4r5
f9DVDN8YmRh1+YEYB8pkFTjZBuz158F9GVRK9r/6Lr2Ft0RAinGiN4LoO+V++Ofk
LITgB0rqMk1UH8XyUJwHkS5btr5M7v7zudiQiUDW4vRpWTJ/I4mb9Y2brMfMxJpg
nJ0ni1pm8Yz8zcVjFklvkdtQD+wx4DXf4/7o2EDBNPc1gW+9gIpCI1h5TMwXWURH
lY9cM03SqKwj6SzHxRdOjcMC1Zie3+8OKr1HYpMT0AIM85T3q1iUif8s0TQ3Mk9o
jQIDAQAB
-----END PUBLIC KEY-----

While you must keep your private key a secret, you can openly share your public key. You can even copy the key multiple times and rename each copy to designate an individual whom you would hand the public key out to.

cp public.key alice-public.key
cp public.key bob-public.key

ls
alice-public.key bob-public.key  private.key  public.key

Now here’s the most critical question that I cannot stress enough:

Who owns these keys?

Does the server that generated this private key own it? Do I, as the author of this blog, own it? Does Amazon, as the company, own this private key?

What about the public keys? Who exactly is Alice (alice-public.key)? Who is Bob (bob-public.key)? How are Bob and Alice different if they have the same public key? These are all rhetorical questions you should be asking yourself when working with cryptographic keys. It helps answer who is responsible for this key and ultimately any data encrypted/unencrypted with that key.

At its core, public key infrastructure (PKI) can be explained as assigning an identity to someone or something and using cryptographic keys to ensure that identity can be verified. In the case of internal PKIs, the someone or something is often a hierarchy of assets belonging to your company. For example, a flow could be:

  • Your company
    • Your company’s business unit
      • business unit servers
      • business unit load balancers
      • business unit clients
    • Another business unit

Step 1: Set up a root certificate authority

You need to start somewhere, right? To get a publicly trusted identity, you often need to go through a certificate management service like AWS Certificate Manager (ACM) or a third-party vendor. These vendors go through several audits with operating system providers to have their identity trusted on the operating system itself. For example, on MacOS, you can open the Keychain Access app, go to System Roots, and look at the Certificates tab to see identities that are managed on your behalf.

In this use case with IAM Roles Anywhere, you don’t have to worry about interacting with operating system providers, because you’re creating your own internal PKI—your own internal identity. You do this by creating a certificate authority.

But hold on now, what exactly is a certificate authority? For that matter, what is a certificate?

A certificate is a wrapper around a public key that assigns metadata to an entity. Remember how you can copy the public key and just rename it to alice-public.key? You’ll need a little more metadata than that but the concept is the same. Examples of metadata include “Who are you?” “Who gave you this key?” “When should this key expire?” “Here is what you’re allowed to use this key for,” and various other attributes. As you can imagine, you don’t want just anybody to provide you this type of metadata. You want trusted authorities to assign or validate that metadata for you, and so the term certificate authorities. Certificate authorities also sign these certificates using a digital signing algorithm such as RSA so that consumers of these certificates can verify that the metadata inside hasn’t been tampered with.

You want to be the certificate authority within your own internal network. So how do you go about doing that? Turns out, you’ve already completed the most critical step: creating a private key. By creating a cryptographically strong, random private key, you can assert that whoever owns this private key, represents our company. You can do so because it’s highly improbable that anyone could guess or brute-force this key. However, that means every mechanism you use to protect this private key is critical.

Remember though, you need an identity, and simply naming your private key anycompany.private.key and public key usecase.public.key isn’t ideal. It’s not ideal because you need a lot more metadata than a file name. You need metadata like you would have in the earlier certificate example. You need a certificate that represents your certificate authority, a sort of ID for your root certificate. To facilitate that, there’s a field in certificates called IsCA that’s either true or false. Meaning whether or not a certificate is simply a certificate or a certificate authority is determined by a flag inside the certificate. We’ll start by writing out an openssl configuration file that is used throughout multiple certificate management commands.

NOTE: What’s the difference between a root certificate and a root certificate authority? You can think of a root certificate authority as a person who stamps other certificates. This person themselves needs an ID card. That ID card is the root certificate.

# NOTE: Examples derived from Ivans Ristic's Github
# https://github.com/ivanr/bulletproof-tls
# You may also use `man ca` at the CLI for more examples

# Basic Info about the CA
[default]
name                    = root-ca
domain_suffix           = example.com
default_ca              = ca_default
name_opt                = utf8,esc_ctrl,multiline,lname,align

[ca_dn]
countryName             = "US"
organizationName        = "Any Company Corp"
commonName              = "internal.anycompany.com"

# How the CA Should operate
[ca_default]
home                    = root-ca
database                = $home/db/index
serial                  = $home/db/serial
certificate             = $home/$name.crt
private_key             = $home/private/$name.key
RANDFILE                = $home/private/random
new_certs_dir           = $home/certs
unique_subject          = no
copy_extensions         = none
default_days            = 3650
default_md              = sha256
policy                  = policy_c_o_match

[policy_c_o_match]
countryName             = match
stateOrProvinceName     = optional
organizationName        = match
organizationalUnitName  = optional
commonName              = supplied
emailAddress            = optional

# Configuration for `req` command
[req]
default_bits            = 4096
encrypt_key             = yes
default_md              = sha256
utf8                    = yes
string_mask             = utf8only
prompt                  = no
distinguished_name      = ca_dn
req_extensions          = ca_ext

[ca_ext]
basicConstraints        = critical,CA:true
keyUsage                = critical,keyCertSign
subjectKeyIdentifier    = hash
# create-root-ca.sh
mkdir -p root-ca/certs   # New Certificates issued are stored here
mkdir -p root-ca/db      # Openssl managed database
mkdir -p root-ca/private # Private key dir for the CA

chmod 700 root-ca/private
touch root-ca/db/index

# Give our root-ca a unique identifier
openssl rand -hex 16 > root-ca/db/serial

# Create the certificate signing request
openssl req -new \
  -config root-ca.conf \
  -out root-ca.csr \
  -keyout root-ca/private/root-ca.key

# Sign our request
openssl ca -selfsign \
  -config root-ca.conf \
  -in root-ca.csr \
  -out root-ca.crt \
  -extensions ca_ext

But there are a few things I have to point out:

  • Most certificates start their lives as a certificate signing request (CSR). They contain most of the data an actual certificate does and only become a certificate when signed either by the same entity that created it (self-signed certificate) or by another entity (external certificate authority). This is why you see openssl req followed by openssl ca -selfsign.
  • Everything under root-ca/ must now be protected, especially anything generated under root-ca/private/.
  • I skipped quite a few steps for the sake of brevity, including creating a subordinate certificate authority and keeping the root certificate authority offline, as well as adding a certificate revocation list and Online Certificate Status Protocol (OSCP) capabilities. These can be their own book and I would instead recommend reading Bulletproof TLS and PKI by Ivan Ristic. In this post, I include the bare minimum to import a certificate and get started with IAM Roles Anywhere. As a side note, if you’re importing a certificate from a certificate authority managed outside of AWS, it should come with these capabilities as well.

It’s good practice to inspect the actual root-ca.crt that was returned to you.

openssl x509 -in root-ca.crt -text -noout

Note: If you want to inspect and compare the root-ca.crt with the certificate signing request root-ca.csr, you can use openssl req -text -noout -verify -in root-ca.csr.

What you look for in the following output are that fields such as Subject, Public-Key Algorithm, and the CA:TRUE flag are set and correspond to the configuration you passed in earlier. Additional things to look for are Issuer (yourself since it’s self-signed), and Key Usage (what the public key included in the certificate is allowed to be used for).

Certificate:
    Data:
        Version: 3 (0x2)
        Serial Number:
            95:77:30:1a:1b:bc:ce:70:f3:e7:ff:1c:12:d2:01:c7
        Signature Algorithm: sha256WithRSAEncryption
        Issuer: C = US, O = Any Company Corp, CN = internal.anycompany.com
        Validity
            Not Before: Jul 5 20:52:33 2023 GMT
            Not After : Jul 2 20:52:33 2033 GMT
        Subject: C = US, O = Any Company Corp, CN = internal.anycompany.com
        Subject Public Key Info:
            Public Key Algorithm: rsaEncryption
                Public-Key: (4096 bit)
                ...
        X509v3 extensions:
            X509v3 Basic Constraints: critical
                CA:TRUE
            X509v3 Key Usage: critical
                Certificate Sign
            ...
    Signature Algorithm: sha256WithRSAEncryption
    Signature Value:
        ...

Now why is this certificate especially important? This is your root certificate. When you’re asked “Does this certificate belong to your company?” this is the certificate that you must use in order to prove that it belongs to your company, including any certificates derived from this root certificate (remember, you can have a hierarchy) and also end-entity certificates (shown later). All certificates derived from this root certificate are cryptographically linked to it through a digital signing algorithm that combines hashing and encryption to sign the certificate (the example above uses sha256WithRSAEncryption).

With your root CA successfully set up, it’s time to integrate it with IAM Roles Anywhere.

Step 2: Set up IAM Roles Anywhere

Step 1: Set up a root certificate authority (root CA) was a prerequisite for using IAM Roles Anywhere. Remember, you set up all this infrastructure to eventually use it. In step 2, you start going through how to effectively use the root CA you set up to issue AWS credentials outside of the AWS ecosystem.

But before you do that, you must bind the IAM Roles Anywhere service to your private certificate authority (private CA). You do this by setting up a trust between the two. When you set up trust between two things, you’re essentially saying “I don’t have the information to verify this is a valid request, so I’m going to trust that the downstream component (in this case, your private CA) knows this information.” Another way of saying it is “if the private CA says it’s good, then it’s a valid request”. You can set up this trust with your newly created root CA by copying the encoded section of your root-ca.crt in the IAM Roles Anywhere console.

To set up the trust

  1. Go the the IAM Roles Anywhere console.
  2. Under External certificate bundle, paste the encoded section of your root-ca.crt.
  3. Submit the form.
tail -n 31 root-ca.crt
-----BEGIN CERTIFICATE-----
MIIFXTCCA0WgAwIBAgIRAJV3MBobvM5w8+f/HBLSAccwDQYJKoZIhvcNAQELBQAw
SDELMAkGA1UEBhMCVVMxGDAWBgNVBAoMD015IENvbXBhbnkgQ29ycDEfMB0GA1UE
...lines removed for brevitity
iCmHNvGCkBMBo08PLPuynuY69IJCdbjv6iudspBQDdu9aYNPF8BWR3dsTjPpsbOw
ef33wuHiCj4nH96wCrSmPoIUfc4UEp7eZiS0A9xHw8TkT5Uzyq9ZThSaTqBZfojD
zGtnpprPTg/lCHDmoTbGmrOp9ByWU3qQUK7ZtzxSjhjT
-----END CERTIFICATE-----
Figure 1: Use the console to set up a trust between IAM Roles Anywhere and the private CA

Figure 1: Use the console to set up a trust between IAM Roles Anywhere and the private CA

What you just set up is a trust anchor, which is a representation of your certificate authority inside of IAM Roles Anywhere. With this trust anchor in place, you can start tying in IAM roles to your authentication. Let’s start with something simple but practical, imagine an on-premises virtual machine (VM) that needs to have read access to Amazon Simple Storage Service (Amazon S3). Not only that, but it must have read only access to a specific folder in Amazon S3 and only that folder.

The first thing you need to do is create an IAM role that trusts IAM Roles Anywhere. But you need to be more specific than that. You need to create a role that trusts IAM Roles Anywhere only when the certificate presented to IAM Roles Anywhere contains the common name MyOnpremVM. If this is unclear, that’s okay, after you have all of the prerequisites set up, you’ll walk through the entire process step by step. The following is the trust section in an IAM policy that can be created in the IAM console.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Principal": {
                "Service": [
                    "rolesanywhere.amazonaws.com"
                ]
            },
            "Action": [
              "sts:AssumeRole",
              "sts:TagSession",
              "sts:SetSourceIdentity"
            ],
            "Condition": {
              "ArnEquals": {
                "aws:SourceArn": [
                  "arn:aws:rolesanywhere:us-east-1:111222333444:trust-anchor/d5302884-5212-4f8d-9b17-24be63a5ae85"
                ]
              },
              "StringEquals": {
                "aws:PrincipalTag/x509Subject/CN": "MyOnpremVM"
              }
            }
        }
    ]
}

The second thing you need to create is the actual Amazon S3 permissions:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "ListObjectsInBucket",
            "Effect": "Allow",
            "Action": "s3:ListBucket",
            "Resource": "arn:aws:s3:::DOC-EXAMPLE-BUCKET",
            "Condition": {
                "StringLike": {
                    "s3:prefix": [
                        "MyOnPremVM/*"
                    ]
                }
            }
        },
        {
            "Effect": "Allow",
            "Action": "s3:*",
            "Resource": [
                "arn:aws:s3:::DOC-EXAMPLE-BUCKET/MyOnPremVM",
                "arn:aws:s3:::DOC-EXAMPLE-BUCKET/MyOnPremVM/*"
            ]
        }
    ]
}

Note: There are other certificate fields you might want to key off as well. See Trust policy in the documentation for more examples.

The last thing to do before moving on is to tie a set of roles to a profile. You can think of it as a container of multiple possible roles with the ability to further restrict them using session policies. Note that you use the role ARN for the S3 role you just created.

aws rolesanywhere create-profile --name DefaultProfile --role-arns arn:aws:iam::111222333444:role/RolesAnywhereS3Role
{
    "profile": {
        "createdAt": "2023-05-01T22:29:36.088864+00:00",
        "createdBy": "arn:aws:sts::111222333444:assumed-role/<role-name>",
        "durationSeconds": 3600,
        "enabled": false,
        "name": "DefaultProfile",
        "profileArn": "arn:aws:rolesanywhere:us-east-1:111222333444:profile/2845dde5-9c82-480d-a6a6-f61240e42d4a",
        "profileId": "2845dde5-9c82-480d-a6a6-f61240e42d4a",
        "roleArns": [
            "arn:aws:iam::111222333444:role/RolesAnywhereS3"
        ],
        "updatedAt": "2023-05-01T22:29:36.088864+00:00"
    }
}

Profiles are created disabled by default, you can enable them later as needed. You could also enable a profile on creation by using the --enabled flag, but I want to highlight the ability to create it as disabled and then enabled it later for awareness. This becomes relevant in cases when you need to disable access, such as during a security event. Use the following command to enable the profile after creating it:

aws rolesanywhere enable-profile --profile-id 2845dde5-9c82-480d-a6a6-f61240e42d4a

Now that all your infrastructure is in place, it’s time to provision an end-entity certificate and assume the role you created earlier.

Creating an end-entity certificate

The first thing you must do is obtain an end-entity certificate. This is called end-entity because a certificate can have an entire chain of certificates that are linked together. The end-entity certificate is at the end of the chain, which commonly represents individual entities, and so the term end-entity certificate.

Similar to how you set up your root certificate, it’s mostly a two-step process. You first create a certificate signing request and then ask someone to sign it (or sign it yourself). You can create a certificate signing request for your on-premises VM with:

# Make your private key specific to your client machine
openssl genpkey -out client.key \
  -algorithm RSA \
  -pkeyopt rsa_keygen_bits:2048
  
# Using your newly generated private key make a certificate signing request
openssl req -new -key client.key -out client.csr

# You'll be presented an interactive session to enter details for the CSR
You are about to be asked to enter information that will be incorporated
into your certificate request.
What you are about to enter is what is called a Distinguished Name or a DN.
There are quite a few fields but you can leave some blank
For some fields there will be a default value,
If you enter '.', the field will be left blank.
-----
Country Name (2 letter code) [XX]:US
State or Province Name (full name) []:WA
Locality Name (eg, city) [Default City]:Seattle
Organization Name (eg, company) [Default Company Ltd]:Any Company Corp
Organizational Unit Name (eg, section) []:Sales
Common Name (eg, your name or your server's hostname) []:MyOnpremVM
Email Address []:

Please enter the following 'extra' attributes
to be sent with your certificate request
A challenge password []:
An optional company name []:

As always, let’s inspect the certificate we made.

openssl req -text -noout -verify -in client.csr

The client name (common name (CN) in the certificate) is what’s most important here, after all this is how we uniquely identify this specific VM.

Certificate Request:
    Data:
        Version: 0 (0x0)
        Subject: C=US, ST=WA, L=Seattle, O=Any Company Corp, OU=Sales, CN=MyOnpremVM
        Subject Public Key Info:
            Public Key Algorithm: rsaEncryption
                Public-Key: (4096 bit)
                Modulus:
                    00:ae:d0:ab:2d:20:2d:44:b5:36:ad:de:dd:23:ac:
                    ...32 lines removed for brevity
                    89:98:ef:b6:86:bf:c2:16:08:55:2d:5e:45:af:24:
                    17:45:cb
                Exponent: 65537 (0x10001)
        Attributes:
            a0:00
    Signature Algorithm: sha256WithRSAEncryption
         08:b4:86:66:14:1f:03:12:0b:36:15:42:2b:ae:56:7b:ba:99:
         ...27 lines removed for brevity
         00:bb:06:88:6b:c7:c2:53

Signing an end-entity certificate

Now that you have your certificate signing request, the certificate must be signed. Let’s have your private root CA that you created in Step 1 sign this certificate.

NOTE: You might have to move your root-ca.crt file into whatever $home is inside of your root-ca.conf file before running the following command.

openssl ca \
  -config root-ca.conf \
  -in client.csr \
  -out client.crt \
  -extensions client_ext

You’ll be asked to manually verify the certificate you’re about to sign. The key things you need to pay attention to for the purposes of IAM Roles Anywhere are:

  • Common Name because that’s how permissions and to what S3 bucket are decided.
  • Key usage specifies Digital Signature, and basic constraints specify CA:FALSE. Both are required to work with IAM Roles Anywhere.
Certificate:
    Data:
        Version: 1 (0x0)
        Serial Number:
            95:77:30:1a:1b:bc:ce:70:f3:e7:ff:1c:12:d2:01:c8
        Issuer:
            countryName               = US
            organizationName          = Any Company Corp
            commonName                = internal.anycompany.com
        Validity
            Not Before: Jul  6 14:46:49 2023 GMT
            Not After : Jul  3 14:46:49 2033 GMT
        Subject:
            countryName               = US
            stateOrProvinceName       = WA
            organizationName          = Any Company Corp
            organizationalUnitName    = Sales
            commonName = MyOnpremVM
        Subject Public Key Info:
            Public Key Algorithm: rsaEncryption
                Public-Key: (2048 bit)
                ...
        X509v3 extensions:
            ...
            X509v3 Basic Constraints: critical
                CA:FALSE
            X509v3 Key Usage: critical
                Digital Signature
            ...
Certificate is to be certified until Jul  3 14:46:49 2033 GMT (3650 days)
Sign the certificate? [y/n]:

After verification, you can commit the certificate to the local database and move on to the next step.

Swapping an end-entity certificate for AWS credentials

Now it’s time for the moment of truth. To review, you have:

  1. Created a local CA
  2. Uploaded the CA certificate into IAM Roles Anywhere and created a trust anchor
  3. Created an IAM role that trusts IAM Roles Anywhere, which in turn trusts your CA certificate
  4. Created an end-entity certificate for a specific server that has been signed by your CA

It’s time to swap this certificate for IAM credentials.

The API you call to swap credentials is CreateSession for IAM Roles Anywhere. This API serves as a wrapper around STS AssumeRole but requires that you pass in certificate information first. You, as the end user, don’t directly call this API. Instead, you use the IAM Roles Anywhere credential helper.

You can get the binary for this helper using the following example command (for Linux).

NOTE: The URL in the example uses version 1.0.4 of the credential helper as there isn’t a latest path. Verify that you’re getting the latest version using the table found inside of IAM roles anywhere documentation.

curl https://rolesanywhere.amazonaws.com/releases/1.0.4/X86_64/Linux/aws_signing_helper --output aws_signing_helper

Then use the credential helper tool to successfully swap for AWS credentials.

NOTE: You pass in the private key, but the private key doesn’t leave the host, it’s used to sign the request to CreateSession. See the signing process to learn more. The signing process is also why you use the credentials helper instead of making a call directly to CreateSession.

./aws_signing_helper credential-process \
  --certificate client.crt \
  --private-key client.key \
  --role-arn arn:aws:iam::111222333444:role/RolesanywhereS3Role \
  --trust-anchor-arn arn:aws:rolesanywhere:us-east-1:111222333444:trust-anchor/d5302884-5212-4f8d-9b17-24be63a5ae85
  --profile-arn arn:aws:rolesanywhere:us-east-1:111222333444:profile/e341077c-4ee6-48e8-8d05-d900eb26b367
{
 "Version":1,
 "AccessKeyId":"ASIAEXAMPLEID",
 "SecretAccessKey":"wWPZTXfKdp8UF6HDpfbTEboEXAMPLESECRETKEY",
 "SessionToken":"IQoJb3JpZ2luX2VjEK///EXAMPLESESSIONTOKEN",
 "Expiration":"2023-05-01T23:37:10Z"
}

You can write the command you just ran into your AWS Config file instead of manually parsing the JSON response into environment variables, or run the serve command to set up a local credential-serving endpoint that’s compatible with the AWS SDK and AWS Command Line Interface (AWS CLI).

./aws_signing_helper serve \
  --certificate client.crt \
  --private-key client.key \
  --role-arn arn:aws:iam::111222333444:role/RolesanywhereS3Role \
  --trust-anchor-arn arn:aws:rolesanywhere:us-east-1:111222333444:trust-anchor/d5302884-5212-4f8d-9b17-24be63a5ae85 \
  --profile-arn arn:aws:rolesanywhere:us-east-1:111222333444:profile/e341077c-4ee6-48e8-8d05-d900eb26b367 \
  & # Start the process in the background

Then export the AWS_EC2_METADATA_SERVICE_ENDPOINT environment variable to point the AWS SDKs and AWS CLI to a local mock EC2 metadata endpoint instead of the endpoint normally found inside EC2 instances.

export AWS_EC2_METADATA_SERVICE_ENDPOINT=http://127.0.0.1:9911/

Then finally, confirm that you assumed the right role with:

aws sts get-caller-identity
{
    "UserId": "AROARIEKBWA5HJMA7JDOJ:00bd58e6934d37bf2c3e19afb4c8cac58c",
    "Account": "111222333444",
    "Arn": "arn:aws:sts::111222333444:assumed-role/RolesAnywhereS3/00bd58e6934d37bf2c3e19afb4c8cac58c"
}

And from here, you can use the AWS CLI or SDKs to make calls into AWS with the permissions you set up. For example, test your permissions by writing an object to Amazon S3 at a location you should be able to write to and a location you shouldn’t be.

# Failure case
aws s3 cp client.crt s3://DOC-EXAMPLE-BUCKET/notme/client.crt
upload failed: ./client.crt to s3://DOC-EXAMPLE-BUCKET/notme/client.crt An error occurred (AccessDenied) when calling the PutObject operation: Access Denied
# Passing Case
aws s3 cp client.crt s3://DOC-EXAMPLE-BUCKET/MyOnPremVM/client.crt
upload: ./client.crt to s3://DOC-EXAMPLE-BUCKET/MyOnPremVM/client.crt

Conclusion

To summarize, I started off this blog post discussing core concepts related to public key infrastructure. I talked about the purpose of keys (being improbable to guess) and certificates (tying an identity to a key, among other important concepts such as digital signing). I then discussed and showed you how to create a local certificate authority (CA), then use that CA to vend out end-entity certificates. Finally, you learned how to establish a trust relationship between your CA and IAM Roles Anywhere to allow IAM Roles Anywhere to verify end-entity certificates and exchange them with AWS credentials.

I encourage you to explore any other openssl commands and scenarios you can imagine. For example, how would you use this information to handle two different fleets of VMs, each with their own unique set of permissions? Another avenue to explore would be using cfssl instead of openssl to create a CA or using a provider such as AWS Private Certificate Authority. You can use an AWS account to try AWS Private Certificate Authority with a 30-day trial. See AWS Private CA Pricing to learn more.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Cody Penta

Cody Penta

Cody Penta is a Solutions Architect at Amazon Web Services and is based out of Charlotte, NC. He has a focus in security and CDK, and enjoys solving the really difficult problems in the technology world. Off the clock, he loves relaxing in the mountains, coding personal projects, and gaming.

Securing generative AI: An introduction to the Generative AI Security Scoping Matrix

Post Syndicated from Matt Saner original https://aws.amazon.com/blogs/security/securing-generative-ai-an-introduction-to-the-generative-ai-security-scoping-matrix/

Generative artificial intelligence (generative AI) has captured the imagination of organizations and is transforming the customer experience in industries of every size across the globe. This leap in AI capability, fueled by multi-billion-parameter large language models (LLMs) and transformer neural networks, has opened the door to new productivity improvements, creative capabilities, and more.

As organizations evaluate and adopt generative AI for their employees and customers, cybersecurity practitioners must assess the risks, governance, and controls for this evolving technology at a rapid pace. As security leaders working with the largest, most complex customers at Amazon Web Services (AWS), we’re regularly consulted on trends, best practices, and the rapidly evolving landscape of generative AI and the associated security and privacy implications. In that spirit, we’d like to share key strategies that you can use to accelerate your own generative AI security journey.

This post, the first in a series on securing generative AI, establishes a mental model that will help you approach the risk and security implications based on the type of generative AI workload you are deploying. We then highlight key considerations for security leaders and practitioners to prioritize when securing generative AI workloads. Follow-on posts will dive deep into developing generative AI solutions that meet customers’ security requirements, best practices for threat modeling generative AI applications, approaches for evaluating compliance and privacy considerations, and will explore ways to use generative AI to improve your own cybersecurity operations.

Where to start

As with any emerging technology, a strong grounding in the foundations of that technology is critical to helping you understand the associated scopes, risks, security, and compliance requirements. To learn more about the foundations of generative AI, we recommend that you start by reading more about what generative AI is, its unique terminologies and nuances, and exploring examples of how organizations are using it to innovate for their customers.

If you’re just starting to explore or adopt generative AI, you might imagine that an entirely new security discipline will be required. While there are unique security considerations, the good news is that generative AI workloads are, at their core, another data-driven computing workload, and they inherit much of the same security regimen. The fact is, if you’ve invested in cloud cybersecurity best practices over the years and embraced prescriptive advice from sources like Steve’s top 10, the Security Pillar of the Well-Architected Framework, and the Well-Architected Machine Learning Lens, you’re well on your way!

Core security disciplines, like identity and access management, data protection, privacy and compliance, application security, and threat modeling are still critically important for generative AI workloads, just as they are for any other workload. For example, if your generative AI application is accessing a database, you’ll need to know what the data classification of the database is, how to protect that data, how to monitor for threats, and how to manage access. But beyond emphasizing long-standing security practices, it’s crucial to understand the unique risks and additional security considerations that generative AI workloads bring. This post highlights several security factors, both new and familiar, for you to consider.

With that in mind, let’s discuss the first step: scoping.

Determine your scope

Your organization has made the decision to move forward with a generative AI solution; now what do you do as a security leader or practitioner? As with any security effort, you must understand the scope of what you’re tasked with securing. Depending on your use case, you might choose a managed service where the service provider takes more responsibility for the management of the service and model, or you might choose to build your own service and model.

Let’s look at how you might use various generative AI solutions in the AWS Cloud. At AWS, security is a top priority, and we believe providing customers with the right tool for the job is critical. For example, you can use the serverless, API-driven Amazon Bedrock with simple-to-consume, pre-trained foundation models (FMs) provided by AI21 Labs, Anthropic, Cohere, Meta, stability.ai, and Amazon Titan. Amazon SageMaker JumpStart provides you with additional flexibility while still using pre-trained FMs, helping you to accelerate your AI journey securely. You can also build and train your own models on Amazon SageMaker. Maybe you plan to use a consumer generative AI application through a web interface or API such as a chatbot or generative AI features embedded into a commercial enterprise application your organization has procured. Each of these service offerings has different infrastructure, software, access, and data models and, as such, will result in different security considerations. To establish consistency, we’ve grouped these service offerings into logical categorizations, which we’ve named scopes.

In order to help simplify your security scoping efforts, we’ve created a matrix that conveniently summarizes key security disciplines that you should consider, depending on which generative AI solution you select. We call this the Generative AI Security Scoping Matrix, shown in Figure 1.

The first step is to determine which scope your use case fits into. The scopes are numbered 1–5, representing least ownership to greatest ownership.

Buying generative AI:

  • Scope 1: Consumer app – Your business consumes a public third-party generative AI service, either at no-cost or paid. At this scope you don’t own or see the training data or the model, and you cannot modify or augment it. You invoke APIs or directly use the application according to the terms of service of the provider.
    Example: An employee interacts with a generative AI chat application to generate ideas for an upcoming marketing campaign.
  • Scope 2: Enterprise app – Your business uses a third-party enterprise application that has generative AI features embedded within, and a business relationship is established between your organization and the vendor.
    Example: You use a third-party enterprise scheduling application that has a generative AI capability embedded within to help draft meeting agendas.

Building generative AI:

  • Scope 3: Pre-trained models – Your business builds its own application using an existing third-party generative AI foundation model. You directly integrate it with your workload through an application programming interface (API).
    Example: You build an application to create a customer support chatbot that uses the Anthropic Claude foundation model through Amazon Bedrock APIs.
  • Scope 4: Fine-tuned models – Your business refines an existing third-party generative AI foundation model by fine-tuning it with data specific to your business, generating a new, enhanced model that’s specialized to your workload.
    Example: Using an API to access a foundation model, you build an application for your marketing teams that enables them to build marketing materials that are specific to your products and services.
  • Scope 5: Self-trained models – Your business builds and trains a generative AI model from scratch using data that you own or acquire. You own every aspect of the model.
    Example: Your business wants to create a model trained exclusively on deep, industry-specific data to license to companies in that industry, creating a completely novel LLM.

In the Generative AI Security Scoping Matrix, we identify five security disciplines that span the different types of generative AI solutions. The unique requirements of each security discipline can vary depending on the scope of the generative AI application. By determining which generative AI scope is being deployed, security teams can quickly prioritize focus and assess the scope of each security discipline.

Let’s explore each security discipline and consider how scoping affects security requirements.

  • Governance and compliance – The policies, procedures, and reporting needed to empower the business while minimizing risk.
  • Legal and privacy – The specific regulatory, legal, and privacy requirements for using or creating generative AI solutions.
  • Risk management – Identification of potential threats to generative AI solutions and recommended mitigations.
  • Controls – The implementation of security controls that are used to mitigate risk.
  • Resilience – How to architect generative AI solutions to maintain availability and meet business SLAs.

Throughout our Securing Generative AI blog series, we’ll be referring to the Generative AI Security Scoping Matrix to help you understand how various security requirements and recommendations can change depending on the scope of your AI deployment. We encourage you to adopt and reference the Generative AI Security Scoping Matrix in your own internal processes, such as procurement, evaluation, and security architecture scoping.

What to prioritize

Your workload is scoped and now you need to enable your business to move forward fast, yet securely. Let’s explore a few examples of opportunities you should prioritize.

Governance and compliance plus Legal and privacy

With consumer off-the-shelf apps (Scope 1) and enterprise off-the-shelf apps (Scope 2), you must pay special attention to the terms of service, licensing, data sovereignty, and other legal disclosures. Outline important considerations regarding your organization’s data management requirements, and if your organization has legal and procurement departments, be sure to work closely with them. Assess how these requirements apply to a Scope 1 or 2 application. Data governance is critical, and an existing strong data governance strategy can be leveraged and extended to generative AI workloads. Outline your organization’s risk appetite and the security posture you want to achieve for Scope 1 and 2 applications and implement policies that specify that only appropriate data types and data classifications should be used. For example, you might choose to create a policy that prohibits the use of personal identifiable information (PII), confidential, or proprietary data when using Scope 1 applications.

If a third-party model has all the data and functionality that you need, Scope 1 and Scope 2 applications might fit your requirements. However, if it’s important to summarize, correlate, and parse through your own business data, generate new insights, or automate repetitive tasks, you’ll need to deploy an application from Scope 3, 4, or 5. For example, your organization might choose to use a pre-trained model (Scope 3). Maybe you want to take it a step further and create a version of a third-party model such as Amazon Titan with your organization’s data included, known as fine-tuning (Scope 4). Or you might create an entirely new first-party model from scratch, trained with data you supply (Scope 5).

In Scopes 3, 4, and 5, your data can be used in the training or fine-tuning of the model, or as part of the output. You must understand the data classification and data type of the assets the solution will have access to. Scope 3 solutions might use a filtering mechanism on data provided through Retrieval Augmented Generation (RAG) with the help from Agents for Amazon Bedrock, for example, as an input to a prompt. RAG offers you an alternative to training or fine-tuning by querying your data as part of the prompt. This then augments the context for the LLM to provide a completion and response that can use your business data as part of the response, rather than directly embedding your data in the model itself through fine-tuning or training. See Figure 3 for an example data flow diagram demonstrating how customer data could be used in a generative AI prompt and response through RAG.

In scopes 4 and 5, on the other hand, you must classify the modified model for the most sensitive level of data classification used to fine-tune or train the model. Your model would then mirror the data classification on the data it was trained against. For example, if you supply PII in the fine-tuning or training of a model, then the new model will contain PII. Currently, there are no mechanisms for easily filtering the model’s output based on authorization, and a user could potentially retrieve data they wouldn’t otherwise be authorized to see. Consider this a key takeaway; your application can be built around your model to implement filtering controls on your business data as part of a RAG data flow, which can provide additional data security granularity without placing your sensitive data directly within the model.

From a legal perspective, it’s important to understand both the service provider’s end-user license agreement (EULA), terms of services (TOS), and any other contractual agreements necessary to use their service across Scopes 1 through 4. For Scope 5, your legal teams should provide their own contractual terms of service for any external use of your models. Also, for Scope 3 and Scope 4, be sure to validate both the service provider’s legal terms for the use of their service, as well as the model provider’s legal terms for the use of their model within that service.

Additionally, consider the privacy concerns if the European Union’s General Data Protection Regulation (GDPR) “right to erasure” or “right to be forgotten” requirements are applicable to your business. Carefully consider the impact of training or fine-tuning your models with data that you might need to delete upon request. The only fully effective way to remove data from a model is to delete the data from the training set and train a new version of the model. This isn’t practical when the data deletion is a fraction of the total training data and can be very costly depending on the size of your model.

Risk management

While AI-enabled applications can act, look, and feel like non-AI-enabled applications, the free-form nature of interacting with an LLM mandates additional scrutiny and guardrails. It is important to identify what risks apply to your generative AI workloads, and how to begin to mitigate them.

There are many ways to identify risks, but two common mechanisms are risk assessments and threat modeling. For Scopes 1 and 2, you’re assessing the risk of the third-party providers to understand the risks that might originate in their service, and how they mitigate or manage the risks they’re responsible for. Likewise, you must understand what your risk management responsibilities are as a consumer of that service.

For Scopes 3, 4, and 5—implement threat modeling—while we will dive deep into specific threats and how to threat-model generative AI applications in a future blog post, let’s give an example of a threat unique to LLMs. Threat actors might use a technique such as prompt injection: a carefully crafted input that causes an LLM to respond in unexpected or undesired ways. This threat can be used to extract features (features are characteristics or properties of data used to train a machine learning (ML) model), defame, gain access to internal systems, and more. In recent months, NIST, MITRE, and OWASP have published guidance for securing AI and LLM solutions. In both the MITRE and OWASP published approaches, prompt injection (model evasion) is the first threat listed. Prompt injection threats might sound new, but will be familiar to many cybersecurity professionals. It’s essentially an evolution of injection attacks, such as SQL injection, JSON or XML injection, or command-line injection, that many practitioners are accustomed to addressing.

Emerging threat vectors for generative AI workloads create a new frontier for threat modeling and overall risk management practices. As mentioned, your existing cybersecurity practices will apply here as well, but you must adapt to account for unique threats in this space. Partnering deeply with development teams and other key stakeholders who are creating generative AI applications within your organization will be required to understand the nuances, adequately model the threats, and define best practices.

Controls

Controls help us enforce compliance, policy, and security requirements in order to mitigate risk. Let’s dive into an example of a prioritized security control: identity and access management. To set some context, during inference (the process of a model generating an output, based on an input) first- or third-party foundation models (Scopes 3–5) are immutable. The API to a model accepts an input and returns an output. Models are versioned and, after release, are static. On its own, the model itself is incapable of storing new data, adjusting results over time, or incorporating external data sources directly. Without the intervention of data processing capabilities that reside outside of the model, the model will not store new data or mutate.

Both modern databases and foundation models have a notion of using the identity of the entity making a query. Traditional databases can have table-level, row-level, column-level, or even element-level security controls. Foundation models, on the other hand, don’t currently allow for fine-grained access to specific embeddings they might contain. In LLMs, embeddings are the mathematical representations created by the model during training to represent each object—such as words, sounds, and graphics—and help describe an object’s context and relationship to other objects. An entity is either permitted to access the full model and the inference it produces or nothing at all. It cannot restrict access at the level of specific embeddings in a vector database. In other words, with today’s technology, when you grant an entity access directly to a model, you are granting it permission to all the data that model was trained on. When accessed, information flows in two directions: prompts and contexts flow from the user through the application to the model, and a completion returns from the model back through the application providing an inference response to the user. When you authorize access to a model, you’re implicitly authorizing both of these data flows to occur, and either or both of these data flows might contain confidential data.

For example, imagine your business has built an application on top of Amazon Bedrock at Scope 4, where you’ve fine-tuned a foundation model, or Scope 5 where you’ve trained a model on your own business data. An AWS Identity and Access Management (IAM) policy grants your application permissions to invoke a specific model. The policy cannot limit access to subsets of data within the model. For IAM, when interacting with a model directly, you’re limited to model access.

{
	"Version": "2012-10-17",
	"Statement": {
		"Sid": "AllowInference",
		"Effect": "Allow",
		"Action": [
			"bedrock:InvokeModel"
		],
		"Resource": "arn:aws:bedrock:*::<foundation-model>/<model-id-of-model-to-allow>
	}
}

What could you do to implement least privilege in this case? In most scenarios, an application layer will invoke the Amazon Bedrock endpoint to interact with a model. This front-end application can use an identity solution, such as Amazon Cognito or AWS IAM Identity Center, to authenticate and authorize users, and limit specific actions and access to certain data accordingly based on roles, attributes, and user communities. For example, the application could select a model based on the authorization of the user. Or perhaps your application uses RAG by querying external data sources to provide just-in-time data for generative AI responses, using services such as Amazon Kendra or Amazon OpenSearch Serverless. In that case, you would use an authorization layer to filter access to specific content based on the role and entitlements of the user. As you can see, identity and access management principles are the same as any other application your organization develops, but you must account for the unique capabilities and architectural considerations of your generative AI workloads.

Resilience

Finally, availability is a key component of security as called out in the C.I.A. triad. Building resilient applications is critical to meeting your organization’s availability and business continuity requirements. For Scope 1 and 2, you should understand how the provider’s availability aligns to your organization’s needs and expectations. Carefully consider how disruptions might impact your business should the underlying model, API, or presentation layer become unavailable. Additionally, consider how complex prompts and completions might impact usage quotas, or what billing impacts the application might have.

For Scopes 3, 4, and 5, make sure that you set appropriate timeouts to account for complex prompts and completions. You might also want to look at prompt input size for allocated character limits defined by your model. Also consider existing best practices for resilient designs such as backoff and retries and circuit breaker patterns to achieve the desired user experience. When using vector databases, having a high availability configuration and disaster recovery plan is recommended to be resilient against different failure modes.

Instance flexibility for both inference and training model pipelines are important architectural considerations in addition to potentially reserving or pre-provisioning compute for highly critical workloads. When using managed services like Amazon Bedrock or SageMaker, you must validate AWS Region availability and feature parity when implementing a multi-Region deployment strategy. Similarly, for multi-Region support of Scope 4 and 5 workloads, you must account for the availability of your fine-tuning or training data across Regions. If you use SageMaker to train a model in Scope 5, use checkpoints to save progress as you train your model. This will allow you to resume training from the last saved checkpoint if necessary.

Be sure to review and implement existing application resilience best practices established in the AWS Resilience Hub and within the Reliability Pillar and Operational Excellence Pillar of the Well Architected Framework.

Conclusion

In this post, we outlined how well-established cloud security principles provide a solid foundation for securing generative AI solutions. While you will use many existing security practices and patterns, you must also learn the fundamentals of generative AI and the unique threats and security considerations that must be addressed. Use the Generative AI Security Scoping Matrix to help determine the scope of your generative AI workloads and the associated security dimensions that apply. With your scope determined, you can then prioritize solving for your critical security requirements to enable the secure use of generative AI workloads by your business.

Please join us as we continue to explore these and additional security topics in our upcoming posts in the Securing Generative AI series.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Matt Saner

Matt Saner

Matt is a Senior Manager leading security specialists at AWS. He and his team help the world’s largest and most complex organizations solve critical security challenges, and help security teams become enablers for their business. Before joining AWS, Matt spent nearly two decades working in the financial services industry, solving various technology, security, risk, and compliance challenges. He highly values life-long learning (security is never static) and holds a Masters in Cybersecurity from NYU. For fun, he’s a pilot who enjoys flying general aviation airplanes.

Mike Lapidakis

Mike Lapidakis

Mike leads the AWS Industries Specialist SA team, comprised of the Security and Compliance, Migration and Modernization, Networking, and Resilience domains. The team helps the largest customers on earth establish a strong foundation to transform their businesses through technical enablement, education, customer advocacy, and executive alignment. Mike has helped organizations modernize on the cloud for over a decade in various architecture and consulting roles.

AWS announces Cloud Companion Guide for the CSA Cyber Trust mark

Post Syndicated from Kimberly Dickson original https://aws.amazon.com/blogs/security/aws-announces-cloud-companion-guide-for-the-csa-cyber-trust-mark/

Amazon Web Services (AWS) is excited to announce the release of a new Cloud Companion Guide to help customers prepare for the Cyber Trust mark developed by the Cyber Security Agency of Singapore (CSA).

The Cloud Companion Guide to the CSA’s Cyber Trust mark provides guidance and a mapping of AWS services and features to applicable domains of the mark. It aims to provide customers with an understanding of which AWS services and tools they can use to help fulfill the requirements set out in the Cyber Trust mark.

The Cyber Trust mark aims to guide organizations to understand their risk profiles and identify relevant cybersecurity preparedness areas required to mitigate these risks. It also serves as a mark of distinction for organizations to show that they have put in place good cybersecurity practices and measures that are commensurate with their cybersecurity risk profile.

The guide does not cover compliance topics such as physical and maintenance controls, or organization-specific requirements such as policies and human resources controls. This makes the guide lightweight and focused on security considerations for AWS services. For a full list of AWS compliance programs, see the AWS Compliance Center.

We hope that organizations of all sizes can use the Cloud Companion Guide for Cyber Trust to implement AWS specific security services and tools to help them achieve effective controls. By understanding which security services and tools are available on AWS, and which controls are applicable to them, customers can build secure workloads and applications on AWS.

“At AWS, security is our top priority, and we remain committed to helping our Singapore customers enhance their cloud security posture, and engender trust from our customers’ end-users,” said Joel Garcia, Head of Technology, ASEAN, “The Cloud Security Companion Guide is one way we work with government agencies such as the Cyber Security Agency of Singapore to do so. Customers who implement these steps can secure their cloud environments better, mitigate risks, and achieve effective controls to build secure workloads on AWS.”

If you have questions or want to learn more, contact your account representative, or leave a comment below.

Want more AWS Security news? Follow us on Twitter.

Kimberly Dickson

Kimberly Dickson

Kimberly is a Security Specialist Solutions Architect at AWS based in Singapore. She is passionate about working with customers on technical security solutions that help them build confidence and operate securely in the cloud.

Leo da Silva

Leo da Silva

Leo is a Principal Security Solutions Architect at AWS who helps customers better utilize cloud services and technologies securely. Over the years, Leo has had the opportunity to work in large, complex environments, designing, architecting, and implementing highly scalable and secure solutions for global companies. He is passionate about football, BBQ, and Jiu Jitsu—the Brazilian version of them all.

Orchestrate Amazon EMR Serverless jobs with AWS Step functions

Post Syndicated from Naveen Balaraman original https://aws.amazon.com/blogs/big-data/orchestrate-amazon-emr-serverless-jobs-with-aws-step-functions/

Amazon EMR Serverless provides a serverless runtime environment that simplifies the operation of analytics applications that use the latest open source frameworks, such as Apache Spark and Apache Hive. With EMR Serverless, you don’t have to configure, optimize, secure, or operate clusters to run applications with these frameworks. You can run analytics workloads at any scale with automatic scaling that resizes resources in seconds to meet changing data volumes and processing requirements. EMR Serverless automatically scales resources up and down to provide just the right amount of capacity for your application, and you only pay for what you use.

AWS Step Functions is a serverless orchestration service that enables developers to build visual workflows for applications as a series of event-driven steps. Step Functions ensures that the steps in the serverless workflow are followed reliably, that the information is passed between stages, and errors are handled automatically.

The integration between AWS Step Functions and Amazon EMR Serverless makes it easier to manage and orchestrate big data workflows. Before this integration, you had to manually poll for job statuses or implement waiting mechanisms through API calls. Now, with the support for “Run a Job (.sync)” integration, you can more efficiently manage your EMR Serverless jobs. Using .sync allows your Step Functions workflow to wait for the EMR Serverless job to complete before moving on to the next step, effectively making job execution part of your state machine. Similarly, the “Request Response” pattern can be useful for triggering a job and immediately getting a response back, all within the confines of your Step Functions workflow. This integration simplifies your architecture by eliminating the need for additional steps to monitor job status, making the whole system more efficient and easier to manage.

In this post, we explain how you can orchestrate a PySpark application using Amazon EMR Serverless and AWS Step Functions. We run a Spark job on EMR Serverless that processes Citi Bike dataset data in an Amazon Simple Storage Service (Amazon S3) bucket and stores the aggregated results in Amazon S3.

Solution Overview

We demonstrate this solution with an example using the Citi Bike dataset. This dataset includes numerous parameters such as Rideable type, Start station, Started at, End station, Ended at, and various other elements about Citi Bikers ride. Our objective is to find the minimum, maximum, and average bike trip duration in a given month.

In this solution, the input data is read from the S3 input path, transformations and aggregations are applied with the PySpark code, and the summarized output is written to the S3 output path s3://<bucket-name>/serverlessout/.

The solution is implemented as follows:

  • Creates an EMR Serverless application with Spark runtime. After the application is created, you can submit the data-processing jobs to that application. This API step waits for Application creation to complete.
  • Submits the PySpark job and waits for its completion with the StartJobRun (.sync) API. This allows you to submit a job to an Amazon EMR Serverless application and wait until the job completes.
  • After the PySpark job completes, the summarized output is available in the S3 output directory.
  • If the job encounters an error, the state machine workflow will indicate a failure. You can inspect the specific error within the state machine. For a more detailed analysis, you can also check the EMR job failure logs in the EMR studio console.

Prerequisites

Before you get started, make sure you have the following prerequisites:

  • An AWS account
  • An IAM user with administrator access
  • An S3 bucket

Solution Architecture

To automate the complete process, we use the following architecture, which integrates Step Functions for orchestration and Amazon EMR Serverless for data transformations. Summarized output is then written to Amazon S3 bucket.

The following diagram illustrates the architecture for this use case

Deployment steps

Before beginning this tutorial, ensure that the role being used to deploy has all the relevant permissions to create the required resources as part of the solution. The roles with the appropriate permissions will be created through a CloudFormation template using the following steps.

Step 1: Create a Step Functions state machine

You can create a Step Functions State Machine workflow in two ways— either through the code directly or through the Step Functions studio graphical interface. To create a state machine, you can follow the steps from either option 1 or option 2 below.

Option 1: Create the state machine through code directly

To create a Step Functions state machine along with the necessary IAM roles, complete the following steps:

  1. Launch the CloudFormation stack using this link. On the Cloud Formation console, provide a stack name and accept the defaults to create the stack. Once the CloudFormation deployment completes, the following resources are created, in addition EMR Service Linked Role will be automatically created by this CloudFormation stack to access EMR Serverless:
    • S3 bucket to upload the PySpark script and write output data from EMR Serverless job. We recommend enabling default encryption on your S3 bucket to encrypt new objects, as well as enabling access logging to log all requests made to the bucket. Following these recommendations will improve security and provide visibility into access of the bucket.
    • EMR Serverless Runtime role that provides granular permissions to specific resources that are required when EMR Serverless jobs run.
    • Step Functions Role to grant AWS Step Functions permissions to access the AWS resources that will be used by its state machines.
    • State Machine with EMR Serverless steps.

  1. To prepare the S3 bucket with PySpark script, open AWS Cloudshell from the toolbar on the top right corner of AWS console and run the following AWS CLI command in CloudShell (make sure to replace <<ACCOUNT-ID>> with your AWS Account ID):

aws s3 cp s3://aws-blogs-artifacts-public/artifacts/BDB-3594/bikeaggregator.py s3://serverless-<<ACCOUNT-ID>>-blog/scripts/

  1. To prepare the S3 bucket with Input data, run the following AWS CLI command in CloudShell (make sure to replace <<ACCOUNT-ID>> with your AWS Account ID):

aws s3 cp s3://aws-blogs-artifacts-public/artifacts/BDB-3594/201306-citibike-tripdata.csv s3://serverless-<<ACCOUNT-ID>>-blog/data/ --copy-props none

Option 2: Create the Step Functions state machine through Workflow Studio

Prerequisites

Before creating the State Machine though Workshop Studio, please ensure that all the relevant roles and resources are created as part of the solution.

  1. To deploy the necessary IAM roles and S3 bucket into your AWS account, launch the CloudFormation stack using this link. Once the CloudFormation deployment completes, the following resources are created:
    • S3 bucket to upload the PySpark script and write output data. We recommend enabling default encryption on your S3 bucket to encrypt new objects, as well as enabling access logging to log all requests made to the bucket. Following these recommendations will improve security and provide visibility into access of the bucket.
    • EMR Serverless Runtime role that provides granular permissions to specific resources that are required when EMR Serverless jobs run.
    • Step Functions Role to grant AWS Step Functions permissions to access the AWS resources that will be used by its state machines.

  1. To prepare the S3 bucket with PySpark script, open AWS Cloudshell from the toolbar on the top right of the AWS console and run the following AWS CLI command in CloudShell (make sure to replace <<ACCOUNT-ID>> with your AWS Account ID):

aws s3 cp s3://aws-blogs-artifacts-public/artifacts/BDB-3594/bikeaggregator.py s3://serverless-<<ACCOUNT-ID>>-blog/scripts/

  1. To prepare the S3 bucket with Input data, run the following AWS CLI command in CloudShell (make sure to replace <<ACCOUNT-ID>> with your AWS Account ID):

aws s3 cp s3://aws-blogs-artifacts-public/artifacts/BDB-3594/201306-citibike-tripdata.csv s3://serverless-<<ACCOUNT-ID>>-blog/data/ --copy-props none

To create a Step Functions state machine, complete the following steps:

  1. On the Step Functions console, choose Create state machine.
  2. Keep the Blank template selected, and click Select.
  3. In the Actions Menu on the left, Step Functions provides a list of AWS services APIs that you can drag and drop into your workflow graph in the design canvas. Type EMR Serverless in the search and drag the Amazon EMR Serverless CreateApplication state to the workflow graph:

  1. In the canvas, select Amazon EMR Serverless CreateApplication state to configure its properties. The Inspector panel on the right shows configuration options. Provide the following Configuration values:
    • Change the State name to Create EMR Serverless Application
    • Provide the following values to the API Parameters. This creates an EMR Serverless Application with Apache Spark based on Amazon EMR release 6.12.0 using default configuration settings.
      {
          "Name": "ServerlessBikeAggr",
          "ReleaseLabel": "emr-6.12.0",
          "Type": "SPARK"
      }

    • Click the Wait for task to complete – optional check box to wait for EMR Serverless Application creation state to complete before executing the next state.
    • Under Next state, select the Add new state option from the drop-down.
  2. Drag EMR Serverless StartJobRun state from the left browser to the next state in the workflow.
    • Rename State name to Submit PySpark Job
    • Provide the following values in the API parameters and click Wait for task to complete – optional (make sure to replace <<ACCOUNT-ID>> with your AWS Account ID).
{
"ApplicationId.$": "$.ApplicationId",
    "ExecutionRoleArn": "arn:aws:iam::<<ACCOUNT-ID>>:role/EMR-Serverless-Role-<<ACCOUNT-ID>>",
    "JobDriver": {
        "SparkSubmit": {
            "EntryPoint": "s3://serverless-<<ACCOUNT-ID>>-blog/scripts/bikeaggregator.py",
            "EntryPointArguments": [
                "s3://serverless-<<ACCOUNT-ID>>-blog/data/",
                "s3://serverless-<<ACCOUNT-ID>>-blog/serverlessout/"
            ],
            "SparkSubmitParameters": "--conf spark.hadoop.hive.metastore.client.factory.class=com.amazonaws.glue.catalog.metastore.AWSGlueDataCatalogHiveClientFactory"
        }
    }
}

  1. Select the Config tab for the state machine from the top and change the following configurations:
    • Change State machine name to EMRServerless-BikeAggr found in Details.
    • In the Permissions section, select StateMachine-Role-<<ACCOUNT-ID>> from the dropdown for Execution role. (Make sure that you replace <<ACCOUNT-ID>> with your AWS Account ID).
  2. Continue to add steps for Check Job Success from the studio as shown in the following diagram.

  1. Click Create to create the Step Functions State Machine for orchestrating the EMR Serverless jobs.

Step 2: Invoke the Step Functions

Now that the Step Function is created, we can invoke it by clicking on the Start execution button:

When the step function is being invoked, it presents its run flow as shown in the following screenshot. Because we have selected Wait for task to complete config (.sync API) for this step, the next step would not start wait until EMR Serverless Application is created (blue represents the Amazon EMR Serverless Application being created).

After successfully creating the EMR Serverless Application, we submit a PySpark Job to that Application.

When the EMR Serverless job completes, the Submit PySpark Job step changes to green. This is because we have selected the Wait for task to complete configuration (using the .sync API) for this step.

The EMR Serverless Application ID as well as PySpark Job run Id from Output tab for Submit PySpark Job step.

Step 3: Validation

To confirm the successful completion of the job, navigate to EMR Serverless console and find the EMR Serverless Application Id. Click the Application Id to find the execution details for the PySpark Job run submitted from the Step Functions.

To verify the output of the job execution, you can check the S3 bucket where the output will be stored in a .csv file as shown in the following graphic.

Cleanup

Log in to the AWS Management Console and delete any S3 buckets created by this deployment to avoid unwanted charges to your AWS account. For example: s3://serverless-<<ACCOUNT-ID>>-blog/

Then clean up your environment, delete the CloudFormation template you created in the Solution configuration steps.

Delete Step function you created as part of this solution.

Conclusion

In this post, we explained how to launch an Amazon EMR Serverless Spark job with Step Functions using Workflow Studio to implement a simple ETL pipeline that creates aggregated output from the Citi Bike dataset and generate reports.

We hope this gives you a great starting point for using this solution with your datasets and applying more complex business rules to solve your transient cluster use cases.

Do you have follow-up questions or feedback? Leave a comment. We’d love to hear your thoughts and suggestions.

References


About the Authors

Naveen Balaraman is a Sr Cloud Application Architect at Amazon Web Services. He is passionate about Containers, Serverless, Architecting Microservices and helping customers leverage the power of AWS cloud.

Karthik Prabhakar is a Senior Big Data Solutions Architect for Amazon EMR at AWS. He is an experienced analytics engineer working with AWS customers to provide best practices and technical advice in order to assist their success in their data journey.

Parul Saxena is a Big Data Specialist Solutions Architect at Amazon Web Services, focused on Amazon EMR, Amazon Athena, AWS Glue and AWS Lake Formation, where she provides architectural guidance to customers for running complex big data workloads over AWS platform. In her spare time, she enjoys traveling and spending time with her family and friends.

Define per-team resource limits for big data workloads using Amazon EMR Serverless

Post Syndicated from Gaurav Sharma original https://aws.amazon.com/blogs/big-data/define-per-team-resource-limits-for-big-data-workloads-using-amazon-emr-serverless/

Customers face a challenge when distributing cloud resources between different teams running workloads such as development, testing, or production. The resource distribution challenge also occurs when you have different line-of-business users. The objective is not only to ensure sufficient resources be consistently available to production workloads and critical teams, but also to prevent adhoc jobs from using all the resources and delaying other critical workloads due to mis-configured or non-optimized code. Cost controls and usage tracking across these teams is also a critical factor.

In the legacy big data and Hadoop clusters as well as Amazon EMR provisioned clusters, this problem was overcome by Yarn resource management and defining what were called Yarn queues for different workloads or teams. Another approach was to allocate independent clusters for different teams or different workloads.

Amazon EMR Serverless is a serverless option in Amazon EMR that makes it straightforward to run your big data workloads using open-source analytics frameworks such as Apache Spark and Hive without the need to configure, manage, or scale the clusters. With EMR Serverless, you don’t have to configure, optimize, secure, or operate clusters to run your workloads. You continue to get the benefits of Amazon EMR, such as open-source compatibility, concurrency, and optimized runtime performance for popular bigdata frameworks. EMR Serverless provides shorter job startup latency, automatic resource management and effective cost controls.

In this post, we show how to define per-team resource limits for big data workloads using EMR serverless.

Solution overview

EMR Serverless comes with a concept called an  EMR Serverless application, which is an isolated environment with the option to choose one of the open source analytics applications(Spark, Hive) to submit your workloads. You can include your own custom libraries, specify your EMR release version, and most importantly define the resource limits for the compute and memory resources. For instance, if your production Spark jobs run on Amazon EMR 6.9.0 and you need to test the same workload on Amazon EMR 6.10.0, you could use EMR Serverless to define EMR 6.10.0 as your version and test your workload using a predefined limit on resources.

The following diagram illustrates our solution architecture. We see that two different teams namely Prod team and Dev team are submitting their jobs independently to two different EMR Applications (namely ProdApp and DevApp respectively ) having dedicated resources.

EMR Serverless provides controls at the account, application and job level to limit the use of resources such as CPU, memory or disk. In the following sections, we discuss some of these controls.

Service quotas at account level

Amazon EMR Serverless has a default quota of 16 for maximum concurrent vCPUs per account. In other words, a new account can have a maximum of 16 vCPUs running at a given point in time in a particular Region across all EMR Serverless applications. However, this quota is auto-adjustable based on the usage patterns, which are monitored at the account and Region levels.

Resource limits and runtime configurations at the application level

In addition to quotas at the account levels, administrators can limit the use of resources at the application level using a feature known as “maximum capacity” which defines the maximum total vCPU, memory and disk capacity that can be consumed collectively by all the jobs running under this application.

You also have an option to specify common runtime and monitoring configurations at the application level which you would otherwise put in the specific job configurations. This helps create a standardized runtime environment for all the jobs running under an application. This can include settings like defining common connection setting your jobs need access to, log configurations that all your jobs will inherit by default, or Spark resource settings to help balance ad-hoc workloads. You can override these configurations at the job level, but defining them at the application can help reduce the configuration necessary for individual jobs.

For further details, refer to Declaring configurations at application level.

Runtime configurations at Job level

After you have set service, application quotas and runtime configurations at application level, you also have an option to override or add new configurations at the job level as well. For example, you can use different Spark job parameters to define how many maximum executors can be run by that specific job. One such parameter is spark.dynamicAllocation.maxExecutors which defines an upper bound for the number of executors in a job and therefore controls the number of workers in an EMR Serverless application because each executor runs within a single worker. This parameter is part of the dynamic allocation feature of Apache Spark, which allows you to dynamically scale the number of executors(workers) registered with the job up and down based on the workload. Dynamic allocation is enabled by default on EMR Serverless. For detailed steps, refer to Declaring configurations at application level.

With these configurations, you can control the resources used across accounts, applications, and jobs. For example, you can create applications with a predefined maximum capacity to constrain costs or configure jobs with resource limits in order to allow multiple ad hoc jobs to run simultaneously without consuming too many resources.

Best practices and considerations

Extending these usage scenarios further, EMR Serverless provides features and capabilities to implement the following design considerations and best practices based on your workload requirements:

  • To make sure that the users or teams submit their jobs only to their approved applications, you could use tag based AWS Identity and Access Management (IAM) policy conditions. For more details, refer to Using tags for access control.
  • You can use custom images as applications belonging to different teams that have distinct use-cases and software requirements. Using custom images is possible EMR 6.9.0 and onwards. Custom images allows you to package various application dependencies into a single container. Some of the important benefits of using custom images include the ability to use your own JDK and Python versions, apply your organization-specific security policies and integrate EMR Serverless into your build, test and deploy pipelines. For more information, refer to Customizing an EMR Serverless image.
  • If you need to estimate how much a Spark job would cost when run on EMR Serverless, you can use the open-source tool EMR Serverless Estimator. This tool analyzes Spark event logs to provide you with the cost estimate. For more details, refer to Amazon EMR Serverless cost estimator
  • We recommend that you determine your maximum capacity relative to the supported worker sizes by multiplying the number of workers by their size. For example, if you want to limit your application with 50 workers to 2 vCPUs, 16 GB of memory and 20 GB of disk, set the maximum capacity to 100 vCPU, 800 GB of memory, and 1000 GB of disk.
  • You can use tags when you create the EMR Serverless application to help search and filter your resources, or track the AWS costs using AWS Cost Explorer. You can also use tags for controlling who can submit jobs to a particular application or modify its configurations. Refer to Tagging your resources for more details.
  • You can configure the pre-initialized capacity at the time of application creation, which keeps the resources ready to be consumed by the time-sensitive jobs you submit.
  • The number of concurrent jobs you can run depends on important factors like maximum capacity limits, workers required for each job, and available IP address if using a VPC.
  • EMR Serverless will setup elastic network interfaces (ENIs) to securely communicate with resources in your VPC. Make sure you have enough IP addresses in your subnet for the job.
  • It’s a best practice to select multiple subnets from multiple Availability Zones. This is because the subnets you select determine the Availability Zones that are available to run the EMR Serverless application. Each worker uses an IP address in the subnet where it is launched. Make sure the configured subnets have enough IP addresses for the number of workers you plan to run.

Resource usage tracking

EMR Serverless not only allows cloud administrators to limit the resources for each application, it also enables them to monitor the applications and track the usage of resources across these applications. For more details, refer to  EMR Serverless usage metrics .

You can also deploy an AWS CloudFormation template to build a sample CloudWatch Dashboard for EMR Serverless which would help visualize various metrics for your applications and jobs. For more information, refer to EMR Serverless CloudWatch Dashboard.

Conclusion

In this post, we discussed how EMR Serverless empowers cloud and data platform administrators to efficiently distribute as well as restrict the cloud resources at different levels, for different organizational units, users and teams, as well as between critical and non-critical workloads. EMR Serverless resource limiting features make sure cloud cost is under control and resource usage is tracked effectively.

For more information on EMR Serverless applications and resource quotas, please refer to EMR Serverless User Guide and Configuring an application.


About the Authors

Gaurav Sharma is a Specialist Solutions Architect(Analytics) at Amazon Web Services (AWS), supporting US public sector customers on their cloud journey. Outside of work, Gaurav enjoys spending time with his family and reading books.

Damon Cortesi is a Principal Developer Advocate with Amazon Web Services. He builds tools and content to help make the lives of data engineers easier. When not hard at work, he still builds data pipelines and splits logs in his spare time.

Enable Security Hub partner integrations across your organization

Post Syndicated from Joaquin Manuel Rinaudo original https://aws.amazon.com/blogs/security/enable-security-hub-partner-integrations-across-your-organization/

AWS Security Hub offers over 75 third-party partner product integrations, such as Palo Alto Networks Prisma, Prowler, Qualys, Wiz, and more, that you can use to send, receive, or update findings in Security Hub.

We recommend that you enable your corresponding Security Hub third-party partner product integrations when you use these partner solutions. By centralizing findings across your AWS and partner solutions in Security Hub, you can get a holistic cross-account and cross-Region view of your security risks. In this way, you can move beyond security reporting and start implementing automations on top of Security Hub that help improve your overall security posture and reduce manual efforts. For example, you can configure your third-party partner offerings to send findings to Security Hub and build standardized enrichment, escalation, and remediation solutions by using Security Hub automation rules, or other AWS services such as AWS Lambda or AWS Step Functions.

To enable partner integrations, you must configure the integration in each AWS Region and AWS account across your organization in AWS Organizations. In this blog post, we’ll show you how to set up a Security Hub partner integration across your entire organization by using AWS CloudFormation StackSets.

Overview

Figure 1 shows the architecture of the solution. The main steps are as follows:

  1. The deployment script creates a CloudFormation template that deploys a stack set across your AWS accounts.
  2. The stack in the member account deploys a CloudFormation custom resource using a Lambda function.
  3. The Lambda function iterates through target Regions and invokes the Security Hub boto3 method enable_import_findings_for_product to enable the corresponding partner integration.

When you add new accounts to the organizational units (OUs), StackSets deploys the CloudFormation stack and the partner integration is enabled.

Figure 1: Diagram of the solution

Figure 1: Diagram of the solution

Prerequisites

To follow along with this walkthrough, make sure that you have the following prerequisites in place:

  • Security Hub enabled across an organization in the Regions where you want to deploy the partner integration.
  • Trusted access with AWS Organizations enabled so that you can deploy CloudFormation StackSets across your organization. For instructions on how to do this, see Activate trusted access with AWS Organizations.
  • Permissions to deploy CloudFormation StackSets in a delegated administrator account for your organization.
  • AWS Command Line Interface (AWS CLI) installed.

Walkthrough

Next, we show you how to get started with enabling your partner integration across your organization using the following solution.

Step 1: Clone the repository

In the AWS CLI, run the following command to clone the aws-securityhub-deploy-partner-integration GitHub repository:

git clone https://github.com/aws-samples/aws-securityhub-partner-integration

Step 2: Set up the integration parameters

  1. Open the parameters.json file and configure the following values:
    • ProductName — Name of the product that you want to enable.
    • ProductArn — The unique Amazon Resource Name (ARN) of the Security Hub partner product. For example, the product ARN for Palo Alto PRISMA Cloud Enterprise, is arn:aws:securityhub:<REGION>:188619942792:product/paloaltonetworks/redlock; and for Prowler, it’s arn:aws:securityhub:<REGION>::product/prowler/prowler. To find a product ARN, see Available third-party partner product integrations.
    • DeploymentTargets — List of the IDs of the OUs of the AWS accounts that you want to configure. For example, use the unique identifier (ID) for the root to deploy across your entire organization.
    • DeploymentRegions — List of the Regions in which you’ve enabled Security Hub, and for which the partner integration should be enabled.
  2. Save the changes and close the file.

Step 3: Deploy the solution

  1. Open a command line terminal of your preference.
  2. Set up your AWS_REGION (for example, export AWS_REGION=eu-west-1) and make sure that your credentials are configured for the delegated administrator account.
  3. Enter the following command to deploy:
    ./setup.sh deploy

Step 4: Verify Security Hub partner integration

To test that the product integration is enabled, run the following command in one of the accounts in the organization. Replace <TARGET-REGION> with one of the Regions where you enabled Security Hub.

aws securityhub list-enabled-products-for-import --region <TARGET-REGION>

Step 5: (Optional) Manage new partners, Regions, and OUs

To add or remove the partner integration in certain Regions or OUs, update the parameters.json file with your desired Regions and OU IDs and repeat Step 3 to redeploy changes to your Security Hub partner integration. You can also directly update the CloudFormation parameters for the securityhub-integration-<PARTNER-NAME> from the CloudFormation console.

To enable new partner integrations, create a new parameters.json file version with the partner’s product name and product ARN to deploy a new stack using the deployment script from Step 3. In the next step, we show you how to disable the partner integrations.

Step 6: Clean up

If needed, you can remove the partner integrations by destroying the stack deployed. To destroy the stack, use the command line terminal configured with the credentials for the AWS StackSets delegated administrator account and run the following command:

 ./setup.sh destroy

You can also directly delete the stack mentioned in Step 5 from the CloudFormation console by accessing the stack page from the CloudFormation console, selecting the stack securityhub-integration-<PARTNER-NAME>, and then choosing Delete.

Conclusion

In this post, you learned how you to enable Security Hub partner integrations across your organization. Now you can configure the partner product of your choice to send, update, or receive Security Hub findings.

You can extend your security automation by using Security Hub automation rules, Amazon EventBridge events, and Lambda functions to start or enrich automated remediation of new ingested findings from partners. For an example of how to do this, see Automated Security Response on AWS.

Developer teams can opt in to configure their own chatbot in AWS Chatbot to receive notifications in Amazon Chime, Slack, or Microsoft Teams channels. Lastly, security teams can use existing bidirectional integrations with Jira Service Management or Jira Core to escalate severe findings to their developer teams.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Security, Identity, & Compliance re:Post or contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Author

Joaquin Manuel Rinaudo

Joaquin is a Principal Security Architect with AWS Professional Services. He is passionate about building solutions that help developers improve their software quality. Prior to AWS, he worked across multiple domains in the security industry, from mobile security to cloud and compliance related topics. In his free time, Joaquin enjoys spending time with family and reading science-fiction novels.

Shachar Hirshberg

Shachar Hirshberg

Shachar is a Senior Product Manager for AWS Security Hub with over a decade of experience in building, designing, launching, and scaling enterprise software. He is passionate about further improving how customers harness AWS services to enable innovation and enhance the security of their cloud environments. Outside of work, Shachar is an avid traveler and a skiing enthusiast.

Validate IAM policies with Access Analyzer using AWS Config rules

Post Syndicated from Anurag Jain original https://aws.amazon.com/blogs/security/validate-iam-policies-with-access-analyzer-using-aws-config-rules/

You can use AWS Identity and Access Management (IAM) Access Analyzer policy validation to validate IAM policies against IAM policy grammar and best practices. The findings generated by Access Analyzer policy validation include errors, security warnings, general warnings, and suggestions for your policy. These findings provide actionable recommendations that help you author policies that are functional and conform to security best practices.

You can use the IAM Policy Validator for AWS CloudFormation and the IAM Policy Validator for Terraform solutions to integrate Access Analyzer policy validation in a proactive manner within your continuous integration and continuous delivery CI/CD pipeline before deploying IAM policies to your Amazon Web Service (AWS) environment. Customers requested a similar capability to validate policies already deployed within their environments as part of the defense-in-depth strategy.

In this post, you learn how to set up and continuously validate and report on compliance of the IAM policies in your environment using AWS Config. AWS Config evaluates the configuration settings of your AWS resources with the help of AWS Config rules, which represent your ideal configuration settings. AWS Config continuously tracks the configuration changes that occur among your resources and checks whether these changes conform to the conditions in your rules. If a resource doesn’t conform to a rule, AWS Config flags the resource and the rule as noncompliant.

You can use this solution to validate identity-based and resource-based IAM policies attached to resources in your AWS environment that might have grammatical or syntactical errors or might not follow AWS best practices. The code used in this post is hosted in a GitHub repository.

Prerequisites

Before you get started, you need:

Step 1: Enable AWS Config to monitor global resources

To get started, enable AWS Config in your AWS account by following the instructions in the AWS Config Developer Guide.

Next, enable the recording of global resources:

  1. Open the AWS Management Console and go to the AWS Config console.
  2. Go to Settings and choose Edit to see the AWS Config recorder settings.
  3. Under General settings, select the Include globally recorded resource types to enable AWS Config to monitor IAM configuration items.
  4. Leave the other settings at their defaults.
  5. Choose Save.
    Figure 1: AWS Config settings page showing inclusion of globally recorded resource types

    Figure 1: AWS Config settings page showing inclusion of globally recorded resource types

  6. After choosing Save, you should see Recording is on at the top of the window.
    Figure 2: AWS Config settings page showing recorder settings

    Figure 2: AWS Config settings page showing recorder settings

    Note: You only need to enable globally recorded resource types in the AWS Region where you’ve configured AWS Config because they aren’t tied to a specific Region and can be used in other Regions. The globally recorded resource types that AWS Config supports are IAM users, groups, roles, and customer managed policies.

Step 2: Deploy the CloudFormation template

In this section, you deploy and test a sample AWS CloudFormation template that creates the following:

  • An AWS Config rule that reports the compliance of IAM policies.
  • An AWS Lambda function that implements and then makes the requests to IAM Access Analyzer and returns the policy validation findings.
  • An IAM role that’s used by the Lambda function with permissions to validate IAM policies using the Access Analyzer ValidatePolicy API.
  • An optional Amazon CloudWatch alarm and Amazon Simple Notification Service (Amazon SNS) topic to provide notification of Lambda function errors.

Follow the steps below to deploy the AWS CloudFormation template:

  1. To deploy the CloudFormation template using the following command, you must have the AWS Command Line Interface (AWS CLI) installed.
  2. Make sure you have configured your AWS CLI credentials.
  3. Clone the solution repository.
    git clone https://github.com/awslabs/aws-iam-access-analyzer-policy-validation-config-rule.git

  4. Navigate to the iam-access-analyzer-config-rule folder of the cloned repository.
    cd aws-iam-access-analyzer-policy-validation-config-rule

  5. Deploy the CloudFormation template using the AWS CLI.

    Note: Change the Region for the parameter — RegionToValidateGlobalResources — to the Region you enabled for global resources in Step 1. Optionally, you can add an email address if you want to receive notifications if the AWS Config rule stops working. Use the code that follows, replacing <us-east-1> with the Region you enabled and <EMAIL_ADDRESS> with your chosen address.

    aws cloudformation deploy \
        --stack-name iam-policy-validation-config-rule \
        --template-file templates/template.yaml \
        --capabilities CAPABILITY_IAM CAPABILITY_NAMED_IAM \
        --parameter-overrides RegionToValidateGlobalResources='<us-east-1>' \
                              ErrorNotificationsEmailAddress='<EMAIL_ADDRESS>'

  6. After successful deployment, you will see the message Successfully created/updated stack – iam-policy-validation-config-rule.
    Figure 3: Successful CloudFormation stack creation reported on the terminal

    Figure 3: Successful CloudFormation stack creation reported on the terminal

    Note: If the CloudFormation stack creation fails, go to the CloudFormation console and select the iam-policy-validation-config-rule stack. Choose Events to review the failure reason.

  7. After deployment, open the CloudFormation console and select the iam-policy-validation-config-rule stack.
  8. Choose Resources to see the resources created by the template.

Step 3: Check noncompliant resources discovered by AWS Config

The AWS Config rule is designed to mark resources that have IAM policies as noncompliant if the resources have validation findings found using the IAM Access Analyzer ValidatePolicy API.

  1. Open the AWS Config console
  2. Choose Rules from the navigation pane on the left and select policy-validation-config-rule.
    Figure 4: AWS Config rules page showing the rule details

    Figure 4: AWS Config rules page showing the rule details

  3. Scroll down on the page and filter Resources in Scope to see the noncompliant resources.
    Figure 5: AWS Config rules page showing noncompliant resources

    Figure 5: AWS Config rules page showing noncompliant resources

    Note: If the AWS Config rule isn’t invoked yet, you can choose Actions and select Re-evaluate to invoke it.

    Figure 6: AWS Config rules page showing evaluation invocation

    Figure 6: AWS Config rules page showing evaluation invocation

Step 4: Modify the AWS Config rule for exceptions

You might want to exempt certain resources from specific policy validation checks. For example, you might need to deploy a more privileged role—such as an administrator role—to your environment and you don’t want that role’s policies to have policy validation findings.

Figure 7: AWS Config rules page showing a noncompliant administrator role

Figure 7: AWS Config rules page showing a noncompliant administrator role

This section shows you how to configure an exceptions file to exempt specific resources.

  1. Start by configuring an exceptions file similar to the one that follows to log general warning findings across the accounts in your organization to make sure your policies conform to best practices by setting ignoreWarningFindings to False.
  2. Additionally, you might want to create an exception that allows administrator roles to use the iam:PassRole action on another role. This combination of action and resource is usually reserved for privileged users. The example file below shows an exception for all the roles created with Administrator in the role path from account 12345678912.

    Example exceptions file:

    {
    "global":{
    "ignoreWarningFindings":false
    },
    "12345678912":{
    "ignoreFindingsWith":[
    {
    "issueCode":"PASS_ROLE_WITH_STAR_IN_ACTION_AND_RESOURCE",
    "resourceType":"AWS::IAM::Role",
    "resourceName":"Administrator/*"
    }
    ]
    }
    }
  3. After the exceptions file is ready, upload the JSON file to the S3 bucket you created as a part of the prerequisites.

    You can manage this exceptions file by hosting it in a central Git repository. When teams need to exempt a particular resource from these policy validation checks, they can submit a pull request to the central repository. An approver can then approve or reject this request and, if approved, deploy the updated exceptions file.

  4. Modify the bucket policy so that the bucket is accessible to your AWS Config rule if the rule is operating in a different account than the bucket was created in. Below is an example of a bucket policy that allows the accounts in your organization to read the exceptions file.
    {
          "Version": "2012-10-17",
          "Statement": [{
              "Effect": "Allow",
              "Principal": {"AWS": "*"},
              "Action": "s3:GetObject",
              "Resource": "arn:aws:s3:::EXAMPLE-BUCKET/my-exceptions-file.json",
              "Condition": {
                  "StringEquals": {
                      "aws:PrincipalOrgId": "<your organization id here>"
                  }
              }
          }]
    }

    Note: For more examples visit example policy validation exceptions file contents.

  5. Deploy the CloudFormation template again using the ExceptionsS3BucketName and ExceptionsS3FilePrefix parameters. The file prefix should be the full prefix of the S3 object exceptions file.
    aws cloudformation deploy \
        --stack-name iam-policy-validation-config-rule \
        --template-file templates/template.yaml \
        --capabilities CAPABILITY_IAM CAPABILITY_NAMED_IAM \
        --parameter-overrides RegionToValidateGlobalResources='<us-east-1>' \
            		ExceptionsS3BucketName='EXAMPLE-BUCKET' \
           		 ExceptionsS3FilePrefix='my-exceptions-file.json'

  6. After you see the Successfully created/updated stack – iam-policy-validation-config-rule message on the terminal or command line and the AWS Config rule has been re-evaluated, the resources mentioned in the exception file should show as Compliant.
    Figure 8: Resource exception result

    Figure 8: Resource exception result

You can find additional customization options in the exceptions file schema.

Cleanup

To avoid recurring charges and to remove the resources used in testing the solution outlined in this post, use the CloudFormation console to delete the iam-policy-validation-config-rule CloudFormation stack.

Figure 9: AWS CloudFormation stack deletion

Figure 9: AWS CloudFormation stack deletion

Conclusion

In this post, we demonstrated how you can set up a centralized compliance and monitoring workflow using AWS IAM Access Analyzer policy validation with AWS Config rules to validate identity-based and resource-based policies attached to resources in your account. Using this solution, you can create a single pane of glass to monitor resources and govern centralized compliance for AWS Config-supported resources across accounts. You can also build and maintain exceptions customized to your environment as shown in the example policy validation exceptions file. You can visit the Access Analyzer policy checks reference page for a complete list of policy check validation errors and resolutions.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Author

Matt Luttrell

Matt is a Sr. Solutions Architect on the AWS Identity Solutions team. When he’s not spending time chasing his kids around, he enjoys skiing, cycling, and the occasional video game.

Swara Gandhi

Swara Gandhi

Swara is a solutions architect on the AWS Identity Solutions team. She works on building secure and scalable end-to-end identity solutions. She is passionate about everything identity, security, and cloud.

How to use AWS Certificate Manager to enforce certificate issuance controls

Post Syndicated from Roger Park original https://aws.amazon.com/blogs/security/how-to-use-aws-certificate-manager-to-enforce-certificate-issuance-controls/

AWS Certificate Manager (ACM) lets you provision, manage, and deploy public and private Transport Layer Security (TLS) certificates for use with AWS services and your internal connected resources. You probably have many users, applications, or accounts that request and use TLS certificates as part of your public key infrastructure (PKI); which means you might also need to enforce specific PKI enterprise controls, such as the types of certificates that can be issued or the validation method used. You can now use AWS Identity and Access Management (IAM) condition context keys to define granular rules around certificate issuance from ACM and help ensure your users are issuing or requesting TLS certificates in accordance with your organizational guidelines.

In this blog post, we provide an overview of the new IAM condition keys available with ACM. We also discuss some example use cases for these condition keys, including example IAM policies. Lastly, we highlight some recommended practices for logging and monitoring certificate issuance across your organization using AWS CloudTrail because you might want to provide PKI administrators a centralized view of certificate activities. Combining preventative controls, like the new IAM condition keys for ACM, with detective controls and comprehensive activity logging can help you meet your organizational requirements for properly issuing and using certificates.

This blog post assumes you have a basic understanding of IAM policies. If you’re new to using identity policies in AWS, see the IAM documentation for more information.

Using IAM condition context keys with ACM to enforce certificate issuance guidelines across your organization

Let’s take a closer look at IAM condition keys to better understand how to use these controls to enforce certificate guidelines. The condition block in an IAM policy is an optional policy element that lets you specify certain conditions for when a policy will be in effect. For instance, you might use a policy condition to specify that no one can delete an Amazon Simple Storage Service (Amazon S3) bucket except for your system administrator IAM role. In this case, the condition element of the policy translates to the exception in the previous sentence: all identities are denied the ability to delete S3 buckets except under the condition that the role is your administrator IAM role. We will highlight some useful examples for certificate issuance later in the post.

When used with ACM, IAM condition keys can now be used to help meet enterprise standards for how certificates are issued in your organization. For example, your security team might restrict the use of RSA certificates, preferring ECDSA certificates. You might want application teams to exclusively use DNS domain validation when they request certificates from ACM, enabling fully managed certificate renewals with little to no action required on your part. Using these condition keys in identity policies or service control policies (SCPs) provide ACM users more control over who can issue certificates with certain configurations. You can now create condition keys to define certificate issuance guardrails around the following:

  • Certificate validation method — Allow or deny a specific validation type (such as email validation).
  • Certificate key algorithm — Allow or deny use of certain key algorithms (such as RSA) for certificates issued with ACM.
  • Certificate transparency (CT) logging — Deny users from disabling CT logging during certificate requests.
  • Domain names — Allow or deny authorized accounts and users to request certificates for specific domains, including wildcard domains. This can be used to help prevent the use of wildcard certificates or to set granular rules around which teams can request certificates for which domains.
  • Certificate authority — Allow or deny use of specific certificate authorities in AWS Private Certificate Authority for certificate requests from ACM.

Before this release, you didn’t always have a proactive way to prevent users from issuing certificates that weren’t aligned with your organization’s policies and best practices. You could reactively monitor certificate issuance behavior across your accounts using AWS CloudTrail, but you couldn’t use an IAM policy to prevent the use of email validation, for example. With the new policy conditions, your enterprise and network administrators gain more control over how certificates are issued and better visibility into inadvertent violations of these controls.

Using service control policies and identity-based policies

Before we showcase some example policies, let’s examine service control policies, or SCPs. SCPs are a type of policy that you can use with AWS Organizations to manage permissions across your enterprise. SCPs offer central control over the maximum available permissions for accounts in your organization, and SCPs can help ensure your accounts stay aligned with your organization’s access control guidelines. You can find more information in Getting started with AWS Organizations.

Let’s assume you want to allow only DNS validated certificates, not email validated certificates, across your entire enterprise. You could create identity-based policies in all your accounts to deny the use of email validated certificates, but creating an SCP that denies the use of email validation across every account in your enterprise would be much more efficient and effective. However, if you only want to prevent a single IAM role in one of your accounts from issuing email validated certificates, an identity-based policy attached to that role would be the simplest, most granular method.

It’s important to note that no permissions are granted by an SCP. An SCP sets limits on the actions that you can delegate to the IAM users and roles in the affected accounts. You must still attach identity-based policies to IAM users or roles to actually grant permissions. The effective permissions are the logical intersection between what is allowed by the SCP and what is allowed by the identity-based and resource-based policies. In the next section, we examine some example policies and how you can use the intersection of SCPs and identity-based policies to enforce enterprise controls around certificates.

Certificate governance use cases and policy examples

Let’s look at some example use cases for certificate governance, and how you might implement them using the new policy condition keys. We’ve selected a few common use cases, but you can find more policy examples in the ACM documentation.

Example 1: Policy to prevent issuance of email validated certificates

Certificates requested from ACM using email validation require manual action by the domain owner to renew the certificates. This could lead to an outage for your applications if the person receiving the email to validate the domain leaves your organization — or is otherwise unable to validate your domain ownership — and the certificate expires without being renewed.

We recommend using DNS validation, which doesn’t require action on your part to automatically renew a public certificate requested from ACM. The following SCP example demonstrates how to help prevent the issuance of email validated certificates, except for a specific IAM role. This IAM role could be used by application teams who cannot use DNS validation and are given an exception.

Note that this policy will only apply to new certificate requests. ACM managed certificate renewals for certificates that were originally issued using email validation won’t be affected by this policy.

{
    "Version":"2012-10-17",
    "Statement":{
        "Effect":"Deny",
        "Action":"acm:RequestCertificate",
        "Resource":"*",
        "Condition":{
            "StringLike" : {
                "acm:ValidationMethod":"EMAIL"
            },
            "ArnNotLike": {
                "aws:PrincipalArn": [ "arn:aws:iam::123456789012:role/AllowedEmailValidation"]
            }
        }
    }
}

Example 2: Policy to prevent issuance of a wildcard certificate

A wildcard certificate contains a wildcard (*) in the domain name field, and can be used to secure multiple sub-domains of a given domain. For instance, *.example.com could be used for mail.example.com, hr.example.com, and dev.example.com. You might use wildcard certificates to reduce your operational complexity, because you can use the same certificate to protect multiple sites on multiple resources (for example, web servers). However, this also means the wildcard certificates have a larger impact radius, because a compromised wildcard certificate could affect each of the subdomains and resources where it’s used. The US National Security Agency warned about the use of wildcard certificates in 2021.

Therefore, you might want to limit the use of wildcard certificates in your organization. Here’s an example SCP showing how to help prevent the issuance of wildcard certificates using condition keys with ACM:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "DenyWildCards",
      "Effect": "Deny",
      "Action": [
        "acm:RequestCertificate"
      ],
      "Resource": [
        "*"
      ],
      "Condition": {
        "ForAnyValue:StringLike": {
          "acm:DomainNames": [
            "${*}.*"
          ]
        }
      }
    }
  ]
}

Notice that in this example, we’re denying a request for a certificate where the leftmost character of the domain name is a wildcard. In the condition section, ForAnyValue means that if a value in the request matches at least one value in the list, the condition will apply. As acm:DomainNames is a multi-value field, we need to specify whether at least one of the provided values needs to match (ForAnyValue), or all the values must match (ForAllValues), for the condition to be evaluated as true. You can read more about multi-value context keys in the IAM documentation.

Example 3: Allow application teams to request certificates for their FQDN but not others

Consider a scenario where you have multiple application teams, and each application team has their own domain names for their workloads. You might want to only allow application teams to request certificates for their own fully qualified domain name (FQDN). In this example SCP, we’re denying requests for a certificate with the FQDN app1.example.com, unless the request is made by one of the two IAM roles in the condition element. Let’s assume these are the roles used for staging and building the relevant application in production, and the roles should have access to request certificates for the domain.

Multiple conditions in the same block must be evaluated as true for the effect to be applied. In this case, that means denying the request. In the first statement, the request must contain the domain app1.example.com for the first part to evaluate to true. If the identity making the request is not one of the two listed roles, then the condition is evaluated as true, and the request will be denied. The request will not be denied (that is, it will be allowed) if the domain name of the certificate is not app1.example.com or if the role making the request is one of the roles listed in the ArnNotLike section of the condition element. The same applies for the second statement pertaining to application team 2.

Keep in mind that each of these application team roles would still need an identity policy with the appropriate ACM permissions attached to request a certificate from ACM. This policy would be implemented as an SCP and would help prevent application teams from giving themselves the ability to request certificates for domains that they don’t control, even if they created an identity policy allowing them to do so.

{
    "Version":"2012-10-17",
    "Statement":[
    {
        "Sid": "AppTeam1",    
        "Effect":"Deny",
        "Action":"acm:RequestCertificate",
        "Resource":"*",      
        "Condition": {
        "ForAnyValue:StringLike": {
          "acm:DomainNames": "app1.example.com"
        },
        "ArnNotLike": {
          "aws:PrincipalARN": [
            "arn:aws:iam::account:role/AppTeam1Staging",
            "arn:aws:iam::account:role/AppTeam1Prod" ]
        }
      }
   },
   {
        "Sid": "AppTeam2",    
        "Effect":"Deny",
        "Action":"acm:RequestCertificate",
        "Resource":"*",      
        "Condition": {
        "ForAnyValue:StringLike": {
          "acm:DomainNames": "app2.example.com"
        },
        "ArnNotLike": {
          "aws:PrincipalARN": [
            "arn:aws:iam::account:role/AppTeam2Staging",
            "arn:aws:iam::account:role/AppTeam2Prod"]
        }
      }
   }
 ] 
}

Example 4: Policy to prevent issuing certificates with certain key algorithms

You might want to allow or restrict a certain certificate key algorithm. For example, allowing the use of ECDSA certificates but restricting RSA certificates from being issued. See this blog post for more information on the differences between ECDSA and RSA certificates, and how to evaluate which type to use for your workload. Here’s an example SCP showing how to deny requests for a certificate that uses one of the supported RSA key lengths.

{
    "Version":"2012-10-17",
    "Statement":{
        "Effect":"Deny",
        "Action":"acm:RequestCertificate",
        "Resource":"*",
        "Condition":{
            "StringLike" : {
                "acm:KeyAlgorithm":"RSA*"
            }
        }
    }
}  

Notice that we’re using a wildcard after RSA to restrict use of RSA certificates, regardless of the key length (for example, 2048, 4096, and so on).

Creating detective controls for better visibility into certificate issuance across your organization

While you can use IAM policy condition keys as a preventative control, you might also want to implement detective controls to better understand certificate issuance across your organization. Combining these preventative and detective controls helps you establish a comprehensive set of enterprise controls for certificate governance. For instance, imagine you use an SCP to deny all attempts to issue a certificate using email validation. You will have CloudTrail logs for RequestCertificate API calls that are denied by this policy, and can use these events to notify the appropriate application team that they should be using DNS validation.

You’re probably familiar with the access denied error message received when AWS explicitly or implicitly denies an authorization request. The following is an example of the error received when a certificate request is denied by an SCP:

"An error occurred (AccessDeniedException) when calling the RequestCertificate operation: User: arn:aws:sts::account:role/example is not authorized to perform: acm:RequestCertificate on resource: arn:aws:acm:us-east-1:account:certificate/* with an explicit deny in a service control policy"

If you use AWS Organizations, you can have a consolidated view of the CloudTrail events for certificate issuance using ACM by creating an organization trail. Please refer to the CloudTrail documentation for more information on security best practices in CloudTrail. Using Amazon EventBridge, you can simplify certificate lifecycle management by using event-driven workflows to notify or automatically act on expiring TLS certificates. Learn about the example use cases for the event types supported by ACM in this Security Blog post.

Conclusion

In this blog post, we discussed the new IAM policy conditions available for use with ACM. We also demonstrated some example use cases and policies where you might use these conditions to provide more granular control on the issuance of certificates across your enterprise. We also briefly covered SCPs, identity-based policies, and how you can get better visibility into certificate governance using services like AWS CloudTrail and Amazon EventBridge. See the AWS Certificate Manager documentation to learn more about using policy conditions with ACM, and then get started issuing certificates with AWS Certificate Manager.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Roger Park

Roger Park

Roger is a Senior Security Content Specialist at AWS Security focusing on data protection. He has worked in cybersecurity for almost ten years as a writer and content producer. In his spare time, he enjoys trying new cuisines, gardening, and collecting records.

Zach Miller

Zach Miller

Zach is a Senior Security Specialist Solutions Architect at AWS. His background is in data protection and security architecture, focused on a variety of security domains, including cryptography, secrets management, and data classification. Today, he is focused on helping enterprise AWS customers adopt and operationalize AWS security services to increase security effectiveness and reduce risk.

Chandan Kundapur

Chandan Kundapur

Chandan is a Principal Product Manager on the AWS Certificate Manager (ACM) team. With over 15 years of cybersecurity experience, he has a passion for driving PKI product strategy.

Brandonn Gorman

Brandonn Gorman

Brandonn is a Senior Software Development Engineer at AWS Cryptography. He has a background in secure system architecture, public key infrastructure management systems, and data storage solutions. In his free time, he explores the national parks, seeks out vinyl records, and trains for races.

Process and analyze highly nested and large XML files using AWS Glue and Amazon Athena

Post Syndicated from Navnit Shukla original https://aws.amazon.com/blogs/big-data/process-and-analyze-highly-nested-and-large-xml-files-using-aws-glue-and-amazon-athena/

In today’s digital age, data is at the heart of every organization’s success. One of the most commonly used formats for exchanging data is XML. Analyzing XML files is crucial for several reasons. Firstly, XML files are used in many industries, including finance, healthcare, and government. Analyzing XML files can help organizations gain insights into their data, allowing them to make better decisions and improve their operations. Analyzing XML files can also help in data integration, because many applications and systems use XML as a standard data format. By analyzing XML files, organizations can easily integrate data from different sources and ensure consistency across their systems, However, XML files contain semi-structured, highly nested data, making it difficult to access and analyze information, especially if the file is large and has complex, highly nested schema.

XML files are well-suited for applications, but they may not be optimal for analytics engines. In order to enhance query performance and enable easy access in downstream analytics engines such as Amazon Athena, it’s crucial to preprocess XML files into a columnar format like Parquet. This transformation allows for improved efficiency and usability in analytics workflows. In this post, we show how to process XML data using AWS Glue and Athena.

Solution overview

We explore two distinct techniques that can streamline your XML file processing workflow:

  • Technique 1: Use an AWS Glue crawler and the AWS Glue visual editor – You can use the AWS Glue user interface in conjunction with a crawler to define the table structure for your XML files. This approach provides a user-friendly interface and is particularly suitable for individuals who prefer a graphical approach to managing their data.
  • Technique 2: Use AWS Glue DynamicFrames with inferred and fixed schemas – The crawler has a limitation when it comes to processing a single row in XML files larger than 1 MB. To overcome this restriction, we use an AWS Glue notebook to construct AWS Glue DynamicFrames, utilizing both inferred and fixed schemas. This method ensures efficient handling of XML files with rows exceeding 1 MB in size.

In both approaches, our ultimate goal is to convert XML files into Apache Parquet format, making them readily available for querying using Athena. With these techniques, you can enhance the processing speed and accessibility of your XML data, enabling you to derive valuable insights with ease.

Prerequisites

Before you begin this tutorial, complete the following prerequisites (these apply to both techniques):

  1. Download the XML files technique1.xml and technique2.xml.
  2. Upload the files to an Amazon Simple Storage Service (Amazon S3) bucket. You can upload them to the same S3 bucket in different folders or to different S3 buckets.
  3. Create an AWS Identity and Access Management (IAM) role for your ETL job or notebook as instructed in Set up IAM permissions for AWS Glue Studio.
  4. Add an inline policy to your role with the iam:PassRole action:
  "Version": "2012-10-17",
  "Statement": [
    {
      "Action": ["iam:PassRole"],
      "Effect": "Allow",
      "Resource": "arn:aws:iam::*:role/AWSGlueServiceRole*",
      "Condition": {
        "StringLike": {
          "iam:PassedToService": ["glue.amazonaws.com"]
        }
      }
    }
}
  1. Add a permissions policy to the role with access to your S3 bucket.

Now that we’re done with the prerequisites, let’s move on to implementing the first technique.

Technique 1: Use an AWS Glue crawler and the visual editor

The following diagram illustrates the simple architecture that you can use to implement the solution.

Processing and Analyzing XML file using AWS Glue and Amazon Athena

To analyze XML files stored in Amazon S3 using AWS Glue and Athena, we complete the following high-level steps:

  1. Create an AWS Glue crawler to extract XML metadata and create a table in the AWS Glue Data Catalog.
  2. Process and transform XML data into a format (like Parquet) suitable for Athena using an AWS Glue extract, transform, and load (ETL) job.
  3. Set up and run an AWS Glue job via the AWS Glue console or the AWS Command Line Interface (AWS CLI).
  4. Use the processed data (in Parquet format) with Athena tables, enabling SQL queries.
  5. Use the user-friendly interface in Athena to analyze the XML data with SQL queries on your data stored in Amazon S3.

This architecture is a scalable, cost-effective solution for analyzing XML data on Amazon S3 using AWS Glue and Athena. You can analyze large datasets without complex infrastructure management.

We use the AWS Glue crawler to extract XML file metadata. You can choose the default AWS Glue classifier for general-purpose XML classification. It automatically detects XML data structure and schema, which is useful for common formats.

We also use a custom XML classifier in this solution. It’s designed for specific XML schemas or formats, allowing precise metadata extraction. This is ideal for non-standard XML formats or when you need detailed control over classification. A custom classifier ensures only necessary metadata is extracted, simplifying downstream processing and analysis tasks. This approach optimizes the use of your XML files.

The following screenshot shows an example of an XML file with tags.

Create a custom classifier

In this step, you create a custom AWS Glue classifier to extract metadata from an XML file. Complete the following steps:

  1. On the AWS Glue console, under Crawlers in the navigation pane, choose Classifiers.
  2. Choose Add classifier.
  3. Select XML as the classifier type.
  4. Enter a name for the classifier, such as blog-glue-xml-contact.
  5. For Row tag, enter the name of the root tag that contains the metadata (for example, metadata).
  6. Choose Create.

Create an AWS Glue Crawler to crawl xml file

In this section, we are creating a Glue Crawler to extract the metadata from XML file using the customer classifier created in previous step.

Create a database

  1. Go to the AWS Glue console, choose Databases in the navigation pane.
  2. Click on Add database.
  3. Provide a name such as blog_glue_xml
  4. Choose Create Database

Create a Crawler

Complete the following steps to create your first crawler:

  1. On the AWS Glue console, choose Crawlers in the navigation pane.
  2. Choose Create crawler.
  3. On the Set crawler properties page, provide a name for the new crawler (such as blog-glue-parquet), then choose Next.
  4. On the Choose data sources and classifiers page, select Not Yet under Data source configuration.
  5. Choose Add a data store.
  6. For S3 path, browse to s3://${BUCKET_NAME}/input/geologicalsurvey/.

Make sure you pick the XML folder rather than the file inside the folder.

  1. Leave the rest of the options as default and choose Add an S3 data source.
  2. Expand Custom classifiers – optional, choose blog-glue-xml-contact, then choose Next and keep the rest of the options as default.
  3. Choose your IAM role or choose Create new IAM role, add the suffix glue-xml-contact (for example, AWSGlueServiceNotebookRoleBlog), and choose Next.
  4. On the Set output and scheduling page, under Output configuration, choose blog_glue_xml for Target database.
  5. Enter console_ as the prefix added to tables (optional) and under Crawler schedule, keep the frequency set to On demand.
  6. Choose Next.
  7. Review all the parameters and choose Create crawler.

Run the Crawler

After you create the crawler, complete the following steps to run it:

  1. On the AWS Glue console, choose Crawlers in the navigation pane.
  2. Open the crawler you created and choose Run.

The crawler will take 1–2 minutes to complete.

  1. When the crawler is complete, choose Databases in the navigation pane.
  2. Choose the database you crated and choose the table name to see the schema extracted by the crawler.

Create an AWS Glue job to convert the XML to Parquet format

In this step, you create an AWS Glue Studio job to convert the XML file into a Parquet file. Complete the following steps:

  1. On the AWS Glue console, choose Jobs in the navigation pane.
  2. Under Create job, select Visual with a blank canvas.
  3. Choose Create.
  4. Rename the job to blog_glue_xml_job.

Now you have a blank AWS Glue Studio visual job editor. On the top of the editor are the tabs for different views.

  1. Choose the Script tab to see an empty shell of the AWS Glue ETL script.

As we add new steps in the visual editor, the script will be updated automatically.

  1. Choose the Job details tab to see all the job configurations.
  2. For IAM role, choose AWSGlueServiceNotebookRoleBlog.
  3. For Glue version, choose Glue 4.0 – Support Spark 3.3, Scala 2, Python 3.
  4. Set Requested number of workers to 2.
  5. Set Number of retries to 0.
  6. Choose the Visual tab to go back to the visual editor.
  7. On the Source drop-down menu, choose AWS Glue Data Catalog.
  8. On the Data source properties – Data Catalog tab, provide the following information:
    1. For Database, choose blog_glue_xml.
    2. For Table, choose the table that starts with the name console_ that the crawler created (for example, console_geologicalsurvey).
  9. On the Node properties tab, provide the following information:
    1. Change Name to geologicalsurvey dataset.
    2. Choose Action and the transformation Change Schema (Apply Mapping).
    3. Choose Node properties and change the name of the transform from Change Schema (Apply Mapping) to ApplyMapping.
    4. On the Target menu, choose S3.
  10. On the Data source properties – S3 tab, provide the following information:
    1. For Format, select Parquet.
    2. For Compression Type, select Uncompressed.
    3. For S3 source type, select S3 location.
    4. For S3 URL, enter s3://${BUCKET_NAME}/output/parquet/.
    5. Choose Node Properties and change the name to Output.
  11. Choose Save to save the job.
  12. Choose Run to run the job.

The following screenshot shows the job in the visual editor.

Create an AWS Gue Crawler to crawl the Parquet file

In this step, you create an AWS Glue crawler to extract metadata from the Parquet file you created using an AWS Glue Studio job. This time, you use the default classifier. Complete the following steps:

  1. On the AWS Glue console, choose Crawlers in the navigation pane.
  2. Choose Create crawler.
  3. On the Set crawler properties page, provide a name for the new crawler, such as blog-glue-parquet-contact, then choose Next.
  4. On the Choose data sources and classifiers page, select Not Yet for Data source configuration.
  5. Choose Add a data store.
  6. For S3 path, browse to s3://${BUCKET_NAME}/output/parquet/.

Make sure you pick the parquet folder rather than the file inside the folder.

  1. Choose your IAM role created during the prerequisite section or choose Create new IAM role (for example, AWSGlueServiceNotebookRoleBlog), and choose Next.
  2. On the Set output and scheduling page, under Output configuration, choose blog_glue_xml for Database.
  3. Enter parquet_ as the prefix added to tables (optional) and under Crawler schedule, keep the frequency set to On demand.
  4. Choose Next.
  5. Review all the parameters and choose Create crawler.

Now you can run the crawler, which takes 1–2 minutes to complete.

You can preview the newly created schema for the Parquet file in the AWS Glue Data Catalog, which is similar to the schema of the XML file.

We now possess data that is suitable for use with Athena. In the next section, we perform data queries using Athena.

Query the Parquet file using Athena

Athena doesn’t support querying the XML file format, which is why you converted the XML file into Parquet for more efficient data querying and use dot notation to query complex types and nested structures.

The following example code uses dot notation to query nested data:

SELECT 
    idinfo.citation.citeinfo.origin,
    idinfo.citation.citeinfo.pubdate,
    idinfo.citation.citeinfo.title,
    idinfo.citation.citeinfo.geoform,
    idinfo.citation.citeinfo.pubinfo.pubplace,
    idinfo.citation.citeinfo.pubinfo.publish,
    idinfo.citation.citeinfo.onlink,
    idinfo.descript.abstract,
    idinfo.descript.purpose,
    idinfo.descript.supplinf,
    dataqual.attracc.attraccr, 
    dataqual.logic,
    dataqual.complete,
    dataqual.posacc.horizpa.horizpar,
    dataqual.posacc.vertacc.vertaccr,
    dataqual.lineage.procstep.procdate,
    dataqual.lineage.procstep.procdesc
FROM "blog_glue_xml"."parquet_parquet" limit 10;

Now that we’ve completed technique 1, let’s move on to learn about technique 2.

Technique 2: Use AWS Glue DynamicFrames with inferred and fixed schemas

In the previous section, we covered the process of handling a small XML file using an AWS Glue crawler to generate a table, an AWS Glue job to convert the file into Parquet format, and Athena to access the Parquet data. However, the crawler encounters limitations when it comes to processing XML files that exceed 1 MB in size. In this section, we delve into the topic of batch processing larger XML files, necessitating additional parsing to extract individual events and conduct analysis using Athena.

Our approach involves reading the XML files through AWS Glue DynamicFrames, employing both inferred and fixed schemas. Then we extract the individual events in Parquet format using the relationalize transformation, enabling us to query and analyze them seamlessly using Athena.

To implement this solution, you complete the following high-level steps:

  1. Create an AWS Glue notebook to read and analyze the XML file.
  2. Use DynamicFrames with InferSchema to read the XML file.
  3. Use the relationalize function to unnest any arrays.
  4. Convert the data to Parquet format.
  5. Query the Parquet data using Athena.
  6. Repeat the previous steps, but this time pass a schema to DynamicFrames instead of using InferSchema.

The electric vehicle population data XML file has a response tag at its root level. This tag contains an array of row tags, which are nested within it. The row tag is an array that contains a set of another row tags, which provide information about a vehicle, including its make, model, and other relevant details. The following screenshot shows an example.

Create an AWS Glue Notebook

To create an AWS Glue notebook, complete the following steps:

  1. Open the AWS Glue Studio console, choose Jobs in the navigation pane.
  2. Select Jupyter Notebook and choose Create.

  1. Enter a name for your AWS Glue job, such as blog_glue_xml_job_Jupyter.
  2. Choose the role that you created in the prerequisites (AWSGlueServiceNotebookRoleBlog).

The AWS Glue notebook comes with a preexisting example that demonstrates how to query a database and write the output to Amazon S3.

  1. Adjust the timeout (in minutes) as shown in the following screenshot and run the cell to create the AWS Glue interactive session.

Create basic Variables

After you create the interactive session, at the end of the notebook, create a new cell with the following variables (provide your own bucket name):

BUCKET_NAME='YOUR_BUCKET_NAME'
S3_SOURCE_XML_FILE = f's3://{BUCKET_NAME}/xml_dataset/'
S3_TEMP_FOLDER = f's3://{BUCKET_NAME}/temp/'
S3_OUTPUT_INFER_SCHEMA = f's3://{BUCKET_NAME}/infer_schema/'
INFER_SCHEMA_TABLE_NAME = 'infer_schema'
S3_OUTPUT_NO_INFER_SCHEMA = f's3://{BUCKET_NAME}/no_infer_schema/'
NO_INFER_SCHEMA_TABLE_NAME = 'no_infer_schema'
DATABASE_NAME = 'blog_xml'

Read the XML file inferring the schema

If you don’t pass a schema to the DynamicFrame, it will infer the schema of the files. To read the data using a dynamic frame, you can use the following command:

df = glueContext.create_dynamic_frame.from_options(
    connection_type="s3",
    connection_options={"paths": [S3_SOURCE_XML_FILE]},
    format="xml",
    format_options={"rowTag": "response"},
)

Print the DynamicFrame Schema

Print the schema with the following code:

df.printSchema()

The schema shows a nested structure with a row array containing multiple elements. To unnest this structure into lines, you can use the AWS Glue relationalize transformation:

df_relationalized = df.relationalize(
    "root", S3_TEMP_FOLDER
)

We are only interested in the information contained within the row array, and we can view the schema by using the following command:

df_relationalized.select("root_row.row").printSchema()

The column names contain row.row, which correspond to the array structure and array column in the dataset. We don’t rename the columns in this post; for instructions to do so, refer to Automate dynamic mapping and renaming of column names in data files using AWS Glue: Part 1. Then you can convert the data to Parquet format and create the AWS Glue table using the following command:


s3output = glueContext.getSink(
  path= S3_OUTPUT_INFER_SCHEMA,
  connection_type="s3",
  updateBehavior="UPDATE_IN_DATABASE",
  partitionKeys=[],
  compression="snappy",
  enableUpdateCatalog=True,
  transformation_ctx="s3output",
)
s3output.setCatalogInfo(
  catalogDatabase="blog_xml", catalogTableName="jupyter_notebook_with_infer_schema"
)
s3output.setFormat("glueparquet")
s3output.writeFrame(df_relationalized.select("root_row.row"))

AWS Glue DynamicFrame provides features that you can use in your ETL script to create and update a schema in the Data Catalog. We use the updateBehavior parameter to create the table directly in the Data Catalog. With this approach, we don’t need to run an AWS Glue crawler after the AWS Glue job is complete.

Read the XML file by setting a schema

An alternative way to read the file is by predefining a schema. To do this, complete the following steps:

  1. Import the AWS Glue data types:
    from awsglue.gluetypes import *

  2. Create a schema for the XML file:
    schema = StructType([ 
      Field("row", StructType([
        Field("row", ArrayType(StructType([
                Field("_2020_census_tract", LongType()),
                Field("__address", StringType()),
                Field("__id", StringType()),
                Field("__position", IntegerType()),
                Field("__uuid", StringType()),
                Field("base_msrp", IntegerType()),
                Field("cafv_type", StringType()),
                Field("city", StringType()),
                Field("county", StringType()),
                Field("dol_vehicle_id", IntegerType()),
                Field("electric_range", IntegerType()),
                Field("electric_utility", StringType()),
                Field("ev_type", StringType()),
                Field("geocoded_column", StringType()),
                Field("legislative_district", IntegerType()),
                Field("make", StringType()),
                Field("model", StringType()),
                Field("model_year", IntegerType()),
                Field("state", StringType()),
                Field("vin_1_10", StringType()),
                Field("zip_code", IntegerType())
        ])))
      ]))
    ])

  3. Pass the schema when reading the XML file:
    df = glueContext.create_dynamic_frame.from_options(
        connection_type="s3",
        connection_options={"paths": [S3_SOURCE_XML_FILE]},
        format="xml",
        format_options={"rowTag": "response", "withSchema": json.dumps(schema.jsonValue())},
    )

  4. Unnest the dataset like before:
    df_relationalized = df.relationalize(
        "root", S3_TEMP_FOLDER
    )

  5. Convert the dataset to Parquet and create the AWS Glue table:
    s3output = glueContext.getSink(
      path=S3_OUTPUT_NO_INFER_SCHEMA,
      connection_type="s3",
      updateBehavior="UPDATE_IN_DATABASE",
      partitionKeys=[],
      compression="snappy",
      enableUpdateCatalog=True,
      transformation_ctx="s3output",
    )
    s3output.setCatalogInfo(
      catalogDatabase="blog_xml", catalogTableName="jupyter_notebook_no_infer_schema"
    )
    s3output.setFormat("glueparquet")
    s3output.writeFrame(df_relationalized.select("root_row.row"))

Query the tables using Athena

Now that we have created both tables, we can query the tables using Athena. For example, we can use the following query:

SELECT * FROM "blog_xml"."jupyter_notebook_no_infer_schema " limit 10;

The following screenshot shows the results.

Clean Up

In this post, we created an IAM role, an AWS Glue Jupyter notebook, and two tables in the AWS Glue Data Catalog. We also uploaded some files to an S3 bucket. To clean up these objects, complete the following steps:

  1. On the IAM console, delete the role you created.
  2. On the AWS Glue Studio console, delete the custom classifier, crawler, ETL jobs, and Jupyter notebook.
  3. Navigate to the AWS Glue Data Catalog and delete the tables you created.
  4. On the Amazon S3 console, navigate to the bucket you created and delete the folders named temp, infer_schema, and no_infer_schema.

Key Takeaways

In AWS Glue, there’s a feature called InferSchema in AWS Glue DynamicFrames. It automatically figures out the structure of a data frame based on the data it contains. In contrast, defining a schema means explicitly stating how the data frame’s structure should be before loading the data.

XML, being a text-based format, doesn’t restrict the data types of its columns. This can cause issues with the InferSchema function. For example, in the first run, a file with column A having a value of 2 results in a Parquet file with column A as an integer. In the second run, a new file has column A with the value C, leading to a Parquet file with column A as a string. Now there are two files on S3, each with a column A of different data types, which can create problems downstream.

The same happens with complex data types like nested structures or arrays. For example, if a file has one tag entry called transaction, it’s inferred as a struct. But if another file has the same tag, it’s inferred as an array

Despite these data type issues, InferSchema is useful when you don’t know the schema or defining one manually is impractical. However, it’s not ideal for large or constantly changing datasets. Defining a schema is more precise, especially with complex data types, but has its own issues, like requiring manual effort and being inflexible to data changes.

InferSchema has limitations, like incorrect data type inference and issues with handling null values. Defining a schema also has limitations, like manual effort and potential errors.

Choosing between inferring and defining a schema depends on the project’s needs. InferSchema is great for quick exploration of small datasets, whereas defining a schema is better for larger, complex datasets requiring accuracy and consistency. Consider the trade-offs and constraints of each method to pick what suits your project best.

Conclusion

In this post, we explored two techniques for managing XML data using AWS Glue, each tailored to address specific needs and challenges you may encounter.

Technique 1 offers a user-friendly path for those who prefer a graphical interface. You can use an AWS Glue crawler and the visual editor to effortlessly define the table structure for your XML files. This approach simplifies the data management process and is particularly appealing to those looking for a straightforward way to handle their data.

However, we recognize that the crawler has its limitations, specifically when dealing with XML files having rows larger than 1 MB. This is where technique 2 comes to the rescue. By harnessing AWS Glue DynamicFrames with both inferred and fixed schemas, and employing an AWS Glue notebook, you can efficiently handle XML files of any size. This method provides a robust solution that ensures seamless processing even for XML files with rows exceeding the 1 MB constraint.

As you navigate the world of data management, having these techniques in your toolkit empowers you to make informed decisions based on the specific requirements of your project. Whether you prefer the simplicity of technique 1 or the scalability of technique 2, AWS Glue provides the flexibility you need to handle XML data effectively.


About the Authors

Navnit Shuklaserves as an AWS Specialist Solution Architect with a focus on Analytics. He possesses a strong enthusiasm for assisting clients in discovering valuable insights from their data. Through his expertise, he constructs innovative solutions that empower businesses to arrive at informed, data-driven choices. Notably, Navnit Shukla is the accomplished author of the book titled “Data Wrangling on AWS.

Patrick Muller works as a Senior Data Lab Architect at AWS. His main responsibility is to assist customers in turning their ideas into a production-ready data product. In his free time, Patrick enjoys playing soccer, watching movies, and traveling.

Amogh Gaikwad is a Senior Solutions Developer at Amazon Web Services. He helps global customers build and deploy AI/ML solutions on AWS. His work is mainly focused on computer vision, and natural language processing and helping customers optimize their AI/ML workloads for sustainability. Amogh has received his master’s in Computer Science specializing in Machine Learning.

Sheela Sonone is a Senior Resident Architect at AWS. She helps AWS customers make informed choices and tradeoffs about accelerating their data, analytics, and AI/ML workloads and implementations. In her spare time, she enjoys spending time with her family – usually on tennis courts.

Get the full benefits of IMDSv2 and disable IMDSv1 across your AWS infrastructure

Post Syndicated from Saju Sivaji original https://aws.amazon.com/blogs/security/get-the-full-benefits-of-imdsv2-and-disable-imdsv1-across-your-aws-infrastructure/

The Amazon Elastic Compute Cloud (Amazon EC2) Instance Metadata Service (IMDS) helps customers build secure and scalable applications. IMDS solves a security challenge for cloud users by providing access to temporary and frequently-rotated credentials, and by removing the need to hardcode or distribute sensitive credentials to instances manually or programmatically. The Instance Metadata Service Version 2 (IMDSv2) adds protections; specifically, IMDSv2 uses session-oriented authentication with the following enhancements:

  • IMDSv2 requires the creation of a secret token in a simple HTTP PUT request to start the session, which must be used to retrieve information in IMDSv2 calls.
  • The IMDSv2 session token must be used as a header in subsequent IMDSv2 requests to retrieve information from IMDS. Unlike a static token or fixed header, a session and its token are destroyed when the process using the token terminates. IMDSv2 sessions can last up to six hours.
  • A session token can only be used directly from the EC2 instance where that session began.
  • You can reuse a token or create a new token with every request.
  • Session token PUT requests are blocked if they contain an X-forwarded-for header.

In a previous blog post, we explained how these new protections add defense-in-depth for third-party and external application vulnerabilities that could be used to try to access the IMDS.

You won’t be able to get the full benefits of IMDSv2 until you disable IMDSv1. While IMDS is provided by the instance itself, the calls to IMDS are from your software. This means your software must support IMDSv2 before you can disable IMDSv1. In addition to AWS SDKs, CLIs, and tools like the SSM agents supporting IMDSv2, you can also use the IMDS Packet Analyzer to pinpoint exactly what you need to update to get your instances ready to use only IMDSv2. These tools make it simpler to transition to IMDSv2 as well as launch new infrastructure with IMDSv1 disabled. All instances launched with AL2023 set the instance to provide only IMDSv2 (IMDSv1 is disabled) by default, with AL2023 also not making IMDSv1 calls.

AWS customers who want to get the benefits of IMDSv2 have told us they want to use IMDSv2 across both new and existing, long-running AWS infrastructure. This blog post shows you scalable solutions to identify existing infrastructure that is providing IMDSv1, how to transition to IMDSv2 on your infrastructure, and how to completely disable IMDSv1. After reviewing this blog, you will be able to set new Amazon EC2 launches to IMDSv2. You will also learn how to identify existing software making IMDSv1 calls, so you can take action to update your software and then require IMDSv2 on existing EC2 infrastructure.

Identifying IMDSv1-enabled EC2 instances

The first step in transitioning to IMDSv2 is to identify all existing IMDSv1-enabled EC2 instances. You can do this in various ways.

Using the console

You can identify IMDSv1-enabled instances using the IMDSv2 attribute column in the Amazon EC2 page in the AWS Management Console.

To view the IMDSv2 attribute column:

  1. Open the Amazon EC2 console and go to Instances.
  2. Choose the settings icon in the top right.
  3. Scroll down to IMDSv2, turn on the slider.
  4. Choose Confirm.

This gives you the IMDS status of your instances. A status of optional means that IMDSv1 is enabled on the instance and required means that IMDSv1 is disabled.

Figure 1: Example of IMDS versions for EC2 instances in the console

Figure 1: Example of IMDS versions for EC2 instances in the console

Using the AWS CLI

You can identify IMDSv1-enabled instances using the AWS Command Line Interface (AWS CLI) by running the aws ec2 describe-instances command and checking the value of HttpTokens. The HttpTokens value determines what version of IMDS is enabled, with optional enabling IMDSv1 and IMDSv2 and required means IMDSv2 is required. Similar to using the console, the optional status indicates that IMDSv1 is enabled on the instance and required indicates that IMDSv1 is disabled.

"MetadataOptions": {
                        "State": "applied", 
                        "HttpEndpoint": "enabled", 
                        "HttpTokens": "optional", 
                        "HttpPutResponseHopLimit": 1
                    },

[ec2-user@ip-172-31-24-101 ~]$ aws ec2 describe-instances | grep '"HttpTokens": "optional"' | wc -l
4

Using AWS Config

AWS Config continually assesses, audits, and evaluates the configurations and relationships of your resources on AWS, on premises, and on other clouds. The AWS Config rule ec2-imdsv2-check checks whether your Amazon EC2 instance metadata version is configured with IMDSv2. The rule is NON_COMPLIANT if the HttpTokens is set to optional, which means the EC2 instance has IMDSv1 enabled.

Figure 2: Example of noncompliant EC2 instances in the AWS Config console

Figure 2: Example of noncompliant EC2 instances in the AWS Config console

After this AWS Config rule is enabled, you can set up AWS Config notifications through Amazon Simple notification Service (Amazon SNS).

Using Security Hub

AWS Security Hub provides detection and alerting capability at the account and organization levels. You can configure cross-Region aggregation in Security Hub to gain insight on findings across Regions. If using AWS Organizations, you can configure a Security Hub designated account to aggregate findings across accounts in your organization.

Security Hub has an Amazon EC2 control ([EC2.8] Amazon EC2 instances should use Instance Metadata Service Version 2 (IMDSv2)) that uses the AWS Config rule ec2-imdsv2-check to check if the instance metadata version is configured with IMDSv2. The rule is NON_COMPLIANT if the HttpTokens is set to optional, which means EC2 instance has IMDSv1 enabled.

Figure 3: Example of AWS Security Hub showing noncompliant EC2 instances

Figure 3: Example of AWS Security Hub showing noncompliant EC2 instances

Using Amazon Event Bridge, you can also set up alerting for the Security Hub findings when the EC2 instances are noncompliant for IMDSv2.

{
  "source": ["aws.securityhub"],
  "detail-type": ["Security Hub Findings - Imported"],
  "detail": {
    "findings": {
      "ProductArn": ["arn:aws:securityhub:us-west-2::product/aws/config"],
      "Title": ["ec2-imdsv2-check"]
    }
  }
}

Identifying if EC2 instances are making IMDSv1 calls

Not all of your software will be making IMDSv1 calls; your dependent libraries and tools might already be compatible with IMDSv2. However, to mitigate against compatibility issues in requiring IMDSv2 and disabling IMDSv1 entirely, you must check for remaining IMDSv1 calls from your software. After you’ve identified that there are instances with IMDSv1 enabled, investigate if your software is making IMDSv1 calls. Most applications make IMDSv1 calls at instance launch and shutdown. For long running instances, we recommend monitoring IMDSv1 calls during a launch or a stop and restart cycle.

You can check whether your software is making IMDSv1 calls by checking the MetadataNoToken metric in Amazon CloudWatch. You can further identify the source of IMDSv1 calls by using the IMDS Packet Analyzer tool.

Steps to check IMDSv1 usage with CloudWatch

  1. Open the CloudWatch console.
  2. Go to Metrics and then All Metrics.
  3. Select EC2 and then choose Per-Instance Metrics.
  4. Search and add the Metric MetadataNoToken for the instances you’re interested in.
Figure 4: CloudWatch dashboard for MetadataNoToken per-instance metric

Figure 4: CloudWatch dashboard for MetadataNoToken per-instance metric

You can use expressions in CloudWatch to view account wide metrics.

SEARCH('{AWS/EC2,InstanceId} MetricName="MetadataNoToken"', 'Maximum')
Figure 5: Using CloudWatch expressions to view account wide metrics for MetadataNoToken

Figure 5: Using CloudWatch expressions to view account wide metrics for MetadataNoToken

You can combine SEARCH and SORT expressions in CloudWatch to help identify the instances using IMDSv1.

SORT(SEARCH('{AWS/EC2,InstanceId} MetricName="MetadataNoToken"', 'Sum', 300), SUM, DESC, 10)
Figure 6: Another example of using CloudWatch expressions to view account wide metrics

Figure 6: Another example of using CloudWatch expressions to view account wide metrics

If you have multiple AWS accounts or use AWS Organizations, you can set up a centralized monitoring account using CloudWatch cross account observability.

IMDS Packet Analyzer

The IMDS Packet Analyzer is an open source tool that identifies and logs IMDSv1 calls from your software, including software start-up on your instance. This tool can assist in identifying the software making IMDSv1 calls on EC2 instances, allowing you to pinpoint exactly what you need to update to get your software ready to use IMDSv2. You can run the IMDS Packet Analyzer from a command line or install it as a service. For more information, see IMDS Packet Analyzer on GitHub.

Disabling IMDSv1 and maintaining only IMDSv2 instances

After you’ve monitored and verified that the software on your EC2 instances isn’t making IMDSv1 calls, you can disable IMDSv1 on those instances. For all compatible workloads, we recommend using Amazon Linux 2023, which offers several improvements (see launch announcement), including requiring IMDSv2 (disabling IMDSv1) by default.

You can also create and modify AMIs and EC2 instances to disable IMDSv1. Configure the AMI provides guidance on how to register a new AMI or change an existing AMI by setting the imds-support parameter to v2.0. If you’re using container services (such as ECS or EKS), you might need a bigger hop limit to help avoid falling back to IMDSv1. You can use the modify-instance-metadata-options launch parameter to make the change. We recommend testing with a hop limit of three in container environments.

To create a new instance

For new instances, you can disable IMDSv1 and enable IMDSv2 by specifying the metadata-options parameter using the run-instance CLI command.

aws ec2 run-instances
    --image-id <ami-0123456789example>
    --instance-type c3.large
    --metadata-options “HttpEndpoint=enabled,HttpTokens=required”

To modify the running instance

aws ec2 modify-instance-metadata-options \
--instance-id <instance-0123456789example> \
--http-tokens required \
--http-endpoint enabled

To configure a new AMI

aws ec2 register-image \
    --name <my-image> \
    --root-device-name /dev/xvda \
    --block-device-mappings DeviceName=/dev/xvda,Ebs={SnapshotId=<snap-0123456789example>} \
    --imds-support v2.0

To modify an existing AMI

aws ec2 modify-image-attribute \
    --image-id <ami-0123456789example> \
    --imds-support v2.0

Using the console

If you’re using the console to launch instances, after selecting Launch Instance from AWS Console, choose the Advanced details tab, scroll down to Metadata version and select V2 only (token required).

Figure 7: Modifying IMDS version using the console

Figure 7: Modifying IMDS version using the console

Using EC2 launch templates

You can use an EC2 launch template as an instance configuration template that an Amazon Auto Scaling group can use to launch EC2 instances. When creating the launch template using the console, you can specify the Metadata version and select V2 only (token required).

Figure 8: Modifying the IMDS version in the EC2 launch templates

Figure 8: Modifying the IMDS version in the EC2 launch templates

Using CloudFormation with EC2 launch templates

When creating an EC2 launch template using AWS CloudFormation, you must specify the MetadataOptions property to use only IMDSv2 by setting HttpTokens as required.

In this state, retrieving the AWS Identity and Access Management (IAM) role credentials always returns IMDSv2 credentials; IMDSv1 credentials are not available.

{
"HttpEndpoint" : <String>,
"HttpProtocolIpv6" : <String>,
"HttpPutResponseHopLimit" : <Integer>,
"HttpTokens" : required,
"InstanceMetadataTags" : <String>
}

Using Systems Manager automation runbook

You can run the EnforceEC2InstanceIMDSv2 automation document available in AWS Systems Manager, which will enforce IMDSv2 on the EC2 instance using the ModifyInstanceMetadataOptions API.

  1. Open the Systems Manager console, and then select Automation from the navigation pane.
  2. Choose Execute automation.
  3. On the Owned by Amazon tab, for Automation document, enter EnforceEC2InstanceIMDSv2, and then press Enter.
  4. Choose EnforceEC2InstanceIMDSv2 document, and then choose Next.
  5. For Execute automation document, choose Simple execution.

    Note: If you need to run the automation on multiple targets, then choose Rate Control.

  6. For Input parameters, enter the ID of EC2 instance under InstanceId
  7. For AutomationAssumeRole, select a role.

    Note: To change the target EC2 instance, the AutomationAssumeRole must have ec2:ModifyInstanceMetadataOptions and ec2:DescribeInstances permissions. For more information about creating the assume role for Systems Manager Automation, see Create a service role for Automation.

  8. Choose Execute.

Using the AWS CDK

If you use the AWS Cloud Development Kit (AWS CDK) to launch instances, you can use it to set the requireImdsv2 property to disable IMDSv1 and enable IMDSv2.

new ec2.Instance(this, 'Instance', {
        // <... other parameters>
        requireImdsv2: true,
})

Using AWS SDK

The new clients for AWS SDK for Java 2.x use IMDSv2, and you can use the new clients to retrieve instance metadata for your EC2 instances. See Introducing a new client in the AWS SDK for Java 2.x for retrieving EC2 Instance Metadata for instructions.

Maintain only IMDSv2 EC2 instances

To maintain only IMDSv2 instances, you can implement service control policies and IAM policies that verify that users and software on your EC2 instances can only use instance metadata using IMDSv2. This policy specifies that RunInstance API calls require the EC2 instance use only IMDSv2. We recommend implementing this policy after all of the instances in associated accounts are free of IMDSv1 calls and you have migrated all of the instances to use only IMDSv2.

{
    "Version": "2012-10-17",
    "Statement": [
               {
            "Sid": "RequireImdsV2",
            "Effect": "Deny",
            "Action": "ec2:RunInstances",
            "Resource": "arn:aws:ec2:*:*:instance/*",
            "Condition": {
                "StringNotEquals": {
                    "ec2:MetadataHttpTokens": "required"
                }
            }
        }
    ]
} 

You can find more details on applicable service control policies (SCPs) and IAM policies in the EC2 User Guide.

Restricting credential usage using condition keys

As an additional layer of defence, you can restrict the use of your Amazon EC2 role credentials to work only when used in the EC2 instance to which they are issued. This control is complementary to IMDSv2 since both can work together. The AWS global condition context keys for EC2 credential control properties (aws:EC2InstanceSourceVPC and aws:EC2InstanceSourcePrivateIPv4) restrict the VPC endpoints and private IPs that can use your EC2 instance credentials, and you can use these keys in service control policies (SCPs) or IAM policies. Examples of these policies are in this blog post.

Conclusion

You won’t be able to get the full benefits of IMDSv2 until you disable IMDSv1. In this blog post, we showed you how to identify IMDSv1-enabled EC2 instances and how to determine if and when your software is making IMDSv1 calls. We also showed you how to disable IMDSv1 on new and existing EC2 infrastructure after your software is no longer making IMDSv1 calls. You can use these tools to transition your existing EC2 instances, and set your new EC2 launches, to use only IMDSv2.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Compute re:Post or contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Saju Sivaji

Saju Sivaji

Saju is Senior Technical Program Manager with the AWS Security organization. When Saju isn’t managing security expectation programs to help raise the security bar for both internal and external customers, he enjoys travelling, racket sports, and bicycling.

Joshua Levinson

Joshua Levinson

Joshua is a Principal Product Manager at AWS on the Amazon EC2 team. He is passionate about helping customers with highly scalable features on EC2 and across AWS and enjoys the challenge of building simplified solutions to complex problems. Outside of work, he enjoys cooking, reading with his kids, and Olympic weightlifting.

Improved resiliency with cluster manager task throttling for Amazon OpenSearch Service

Post Syndicated from Dhwanil Patel original https://aws.amazon.com/blogs/big-data/improved-resiliency-with-cluster-manager-task-throttling-for-amazon-opensearch-service/

Amazon OpenSearch Service is a managed service that makes it simple to secure, deploy, and operate OpenSearch clusters at scale in the AWS Cloud. Amazon OpenSearch clusters are comprised of data nodes and cluster manager nodes. The cluster manager nodes elect a leader among themselves. The leader node is the authority on the metadata in the cluster, which is called cluster state. Any changes to the cluster state are processed by the leader node and broadcasted to all of the nodes in the cluster. The data nodes enqueue a new cluster-level task for any cluster state change like creation of an index, dynamic put-mappings, shard started, etc. in the cluster manager’s unbounded queue. The tasks waiting in this queue are called pending tasks. Because it’s unbounded, a large number of pending tasks can be queued, which overloads the leader node. This can affect the leader’s performance and may also in turn affect the stability and availability of the whole cluster.

We have introduced a throttling mechanism for cluster manager nodes to provide protection against a large number of pending tasks. It acts during task submission to the leader node. This feature is available for Amazon OpenSearch engine version 1.3 and above in Amazon OpenSearch Service.

Cluster manager task throttling

Cluster manager task throttling is a mechanism to protect the cluster manager against submission of too many resource-intensive cluster state update tasks from other nodes. For tasks like put-mapping, data nodes have an existing throttling mechanism for cluster-state tasks that helps avoid overload of the cluster manager. For example, if the cluster manager can handle 10 K requests and the domain has 10 data nodes, then each data node gets a throttle at 1,000 put-mapping requests. If the domain grows to 100 data nodes, then each data node must throttle at 100 requests. To avoid having to modify these throttle limit whenever the cluster changes the number of data nodes and to support more task types, we ‘ve introduced throttling at cluster manager node for self-protection.

The cluster state update tasks are of different types ( create-index, put-mapping, and more) and this throttling mechanism rejects a task based on its type. For any incoming task, the cluster manager evaluates the total number of tasks of the same type in the pending task queue. If this number exceeds the threshold for a task type, then the cluster manager rejects the incoming task.

Amazon OpenSearch Service configures different throttling thresholds for different task types and throttling acts independently on each task type. Rejecting a particular task doesn’t affect other tasks of a different type. For example, if the cluster manager rejects a put-mapping task, it can still accept a concurrent create-index task.

All of the tasks generated by data plane APIs( _mapping/, _setting/ and more) have been onboarded for throttling and are listed here.

When the cluster manager rejects a task, the data node performs retries with exponential back off to resubmit the task to the cluster manager until it is successfully submitted. If retries are unsuccessful within the timeout period, then Amazon OpenSearch returns a cluster timeout error.

Sample of error

{
  "error" : {
    "type" : "process_cluster_event_timeout_exception",
    "reason" : "failed to process cluster event (indices:admin/mapping/put) within 30s",
    "suppressed" : [
      {
        "type" : "cluster_manager_throttling_exception",
        "reason" : "Throttling Exception : Limit exceeded for put-mapping"
      }
    ]
  },
  "status" : 503
}

Handling time out errors

The throttling exception is acted upon by data nodes; they perform the retries on throttled task. If API times out during throttling period, you’ll get process_cluster_event_timeout_exception , which is a 503 error. This is the same error that was thrown earlier as well when tasks are timing out in the cluster manager node’s queue. You can retry the API calls with timeout errors.

This solution will improve this feature by exposing the throttling exception directly as an API error.

Monitoring throttling

You can monitor the detailed throttling stats using the _nodes/stats API.

curl -XGET "https://{endpoint}/_nodes/stats/cluster_manager_throttling?pretty"

You can use the cluster_manager_throttling section in the _nodes/stats response to track, which tasks are getting throttled and how many tasks has been throttled.

Sample response

    "cluster_manager_throttling" : {
        "cluster_manager_stats" : {
          "TotalThrottledTasks" : 18,
          "ThrottledTasksPerTaskType" : {
            "put-mapping" : 18
          }
        }
    }

Conclusion

In this post, we showed you how a throttling mechanism for task submission to the cluster manager node makes it more resilient to a high number of pending tasks in Amazon OpenSearch Service, where we have fine-tuned the thresholds per cluster.

Cluster manager throttling is available in Amazon OpenSearch, and we are always looking for external contributions. You can refer to the RFC (Request For Comment) to get started.


About the Authors

Dhwanil Patel is a Software Developer Engineer working on Amazon OpenSearch Service. He likes to contribute to open-source software development, and is passionate about distributed systems.

Shweta Thareja is a Principal Engineer working on Amazon OpenSearch Service. She is interested in building distributed and autonomous systems. She is a maintainer and an active contributor to OpenSearch.

Jon Handler is a Senior Principal Solutions Architect at Amazon Web Services based in Palo Alto, CA. Jon works closely with OpenSearch and Amazon OpenSearch Service, providing help and guidance to a broad range of customers who have search and log analytics workloads that they want to move to the AWS Cloud. Prior to joining AWS, Jon’s career as a software developer included 4 years of coding a large-scale, ecommerce search engine. Jon holds a Bachelor of the Arts from the University of Pennsylvania, and a Master of Science and a PhD in Computer Science and Artificial Intelligence from Northwestern University.

Deploy AWS WAF faster with Security Automations

Post Syndicated from Harith Gaddamanugu original https://aws.amazon.com/blogs/security/deploy-aws-managed-rules-using-security-automations-for-aws-waf/

You can now deploy AWS WAF managed rules as part of the Security Automations for AWS WAF solution. In this post, we show you how to get started and set up monitoring for this automated solution with additional recommendations.

This article discusses AWS WAF, a service that assists you in protecting against typical web attacks and bots that might disrupt availability, compromise security, or consume excessive resources. As requests for your websites are received by the underlying service, they’re forwarded to AWS WAF for inspection against your rules. AWS WAF informs the underlying service to either block, allow, or take another configured action when a request fulfills the criteria stated in your rules. AWS WAF is tightly integrated with Amazon CloudFront, Application Load Balancer (ALB), Amazon API Gateway, and AWS AppSync—all of which are routinely used by AWS customers to provide content for their websites and applications.

To provide a simple, purpose-driven deployment approach, our solutions builder teams developed Security Automations for AWS WAF, a solution that can help organizations that don’t have dedicated security teams to quickly deploy an AWS WAF that filters common web-based malicious activity. Security Automations for AWS WAF deploys a set of preconfigured rules to help you protect your applications from common web exploits.

This solution can be installed in your AWS accounts by launching the provided AWS CloudFormation template.

Security Automations for AWS WAF provides the following features and benefits:

  • Helps secure your web applications with AWS managed rule groups
  • Provide layer 7 flood protection with a predefined HTTP flood custom rule
  • Helps block exploitation of vulnerabilities with a predefined scanners and probes custom rule
  • Detect and deflect intrusion from bots with a honeypot endpoint using a bad bot custom rule
  • Helps block malicious IP addresses based on AWS and external IP reputation lists
  • Building a monitoring dashboard with Amazon CloudWatch
  • Integration with AWS Service Catalog AppRegistry and AWS Systems Manager Application Manager
Figure 1: Design overview of the new Security Automations for AWS WAF solution

Figure 1: Design overview of the new Security Automations for AWS WAF solution

Getting started

Many customers begin their proofs of concept (POC) by using the AWS Management Console for AWS WAF to set up their very first AWS WAF, but quickly realize the benefits of automation, such as increased productivity, enforcing best practices, avoiding repetition, and so on. Manually managing AWS WAF can be time-consuming, especially if you want to duplicate complicated automations across multiple environments.

You can deploy this solution for new and existing supported AWS WAF resources. The implementation guide discusses architectural considerations, configuration steps, and operational best practices for deploying this solution in the AWS Cloud. It includes links to AWS CloudFormation templates and stacks that launch, configure, and run the AWS security, compute, storage, and other services required to deploy this solution on AWS, using AWS best practices for security and availability.

Before you launch the CloudFormation template, review the architecture and configuration considerations discussed in this guide. The template takes about 15 minutes to deploy and includes three basic steps:

Step 1. Launch the stack

  1. Launch the CloudFormation template into your AWS account and select the desired AWS Region.
  2. Enter values for the required parameters: Stack name and Application access log bucket name.
  3. Review the other template parameters and adjust if necessary.

Step 2. Associate the web ACL with your web application

Associate your CloudFront web distributions or ALBs with the web ACL that this solution generates. You can associate as many distributions or load balancers as you want.

Step 3. Configure web access logging

Turn on web access logging for your CloudFront web distributions or ALBs, and send the log files to the appropriate Amazon Simple Storage Service (Amazon S3) bucket. Save the logs in a folder matching the user-defined prefix. If no user-defined prefix is used, save the logs to AWSLogs (default log prefix AWSLogs/).

Customize the solution

This solution provides an example of how to use AWS WAF and other services to build security automations on the AWS Cloud. You can download the open source code from GitHub to apply customizations or build your own security automations that fit your needs. The solution builder team is planning to release a Terraform version for this solution in the near future.

Monitor the solution

This solution includes a Service Catalog AppRegistry resource to register the CloudFormation template and underlying resources as an application in both the Service Catalog AppRegistry and Systems Manager Application Manager. You can monitor the costs and operations data in the Systems Manager console, as shown in Figure 2 that follows.

Figure 2: Example of the application view for the Security Automations for AWS WAF stack in Application Manager

Figure 2: Example of the application view for the Security Automations for AWS WAF stack in Application Manager

CloudWatch dashboards are customizable home pages in the CloudWatch console that you can use to monitor your resources in a single view, including visualizing AWS WAF logs as shown in Figure 3 that follows. The solution creates a simple dashboard that you can customize to monitor additional metrics, alarms and logs. If suspicious activity is reported, you can use the visuals to understand the traffic in more detail and drive incident response actions as needed. From here, you can investigate further by using specific queries with CloudWatch Logs Insights.

Figure 3: Example of an enhanced AWS WAF CloudWatch dashboard that can be built for monitoring your site traffic

Figure 3: Example of an enhanced AWS WAF CloudWatch dashboard that can be built for monitoring your site traffic

Conclusion

In this post, you learned about using the AWS Security Automation template to quickly deploy AWS WAF. If you prefer a simpler solution, we recommend using the one-click CloudFront AWS WAF setup, which offers a simple way to deploy AWS WAF for your CloudFront distribution. By choosing the approach that aligns with your requirements, you can enhance the security of your web applications and safeguard them against potential threats.

For more solutions, visit the AWS Solutions Library.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Harith Gaddamanugu

Harith Gaddamanugu

Harith works at AWS as a Sr. Edge Specialist Solutions Architect. He stays motivated by solving problems for customers across AWS Perimeter Protection and Edge services. When he is not working, he enjoys spending time outdoors with friends and family.

Enable external pipeline deployments to AWS Cloud by using IAM Roles Anywhere

Post Syndicated from Olivier Gaumond original https://aws.amazon.com/blogs/security/enable-external-pipeline-deployments-to-aws-cloud-by-using-iam-roles-anywhere/

Continuous integration and continuous delivery (CI/CD) services help customers automate deployments of infrastructure as code and software within the cloud. Common native Amazon Web Services (AWS) CI/CD services include AWS CodePipeline, AWS CodeBuild, and AWS CodeDeploy. You can also use third-party CI/CD services hosted outside the AWS Cloud, such as Jenkins, GitLab, and Azure DevOps, to deploy code within the AWS Cloud through temporary security credentials use.

Security credentials allow identities (for example, IAM role or IAM user) to verify who they are and the permissions they have to interact with another resource. The AWS Identity and Access Management (IAM) service authentication and authorization process requires identities to present valid security credentials to interact with another AWS resource.

According to AWS security best practices, where possible, we recommend relying on temporary credentials instead of creating long-term credentials such as access keys. Temporary security credentials, also referred to as short-term credentials, can help limit the impact of inadvertently exposed credentials because they have a limited lifespan and don’t require periodic rotation or revocation. After temporary security credentials expire, AWS will no longer approve authentication and authorization requests made with these credentials.

In this blog post, we’ll walk you through the steps on how to obtain AWS temporary credentials for your external CI/CD pipelines by using IAM Roles Anywhere and an on-premises hosted server running Azure DevOps Services.

Deploy securely on AWS using IAM Roles Anywhere

When you run code on AWS compute services, such as AWS Lambda, AWS provides temporary credentials to your workloads. In hybrid information technology environments, when you want to authenticate with AWS services from outside of the cloud, your external services need AWS credentials.

IAM Roles Anywhere provides a secure way for your workloads — such as servers, containers, and applications running outside of AWS — to request and obtain temporary AWS credentials by using private certificates. You can use IAM Roles Anywhere to enable your applications that run outside of AWS to obtain temporary AWS credentials, helping you eliminate the need to manage long-term credentials or complex temporary credential solutions for workloads running outside of AWS.

To use IAM Roles Anywhere, your workloads require an X.509 certificate, issued by your private certificate authority (CA), to request temporary security credentials from the AWS Cloud.

IAM Roles Anywhere can work with your existing client or server certificates that you issue to your workloads today. In this blog post, our objective is to show how you can use X.509 certificates issued by your public key infrastructure (PKI) solution to gain access to AWS resources by using IAM Roles Anywhere. Here we don’t cover PKI solutions options, and we assume that you have your own PKI solution for certificate generation. In this post, we demonstrate the IAM Roles Anywhere setup with a self-signed certificate for the purpose of the demo running in a test environment.

External CI/CD pipeline deployments in AWS

CI/CD services are typically composed of a control plane and user interface. They are used to automate the configuration, orchestration, and deployment of infrastructure code or software. The code build steps are handled by a build agent that can be hosted on a virtual machine or container running on-premises or in the cloud. Build agents are responsible for completing the jobs defined by a CI/CD pipeline.

For this use case, you have an on-premises CI/CD pipeline that uses AWS CloudFormation to deploy resources within a target AWS account. The CloudFormation template, the pipeline definition, and other files are hosted in a Git repository. The on-premises build agent requires permissions to deploy code through AWS CloudFormation within an AWS account. To make calls to AWS APIs, the build agent needs to obtain AWS credentials from an IAM role. The solution architecture is shown in Figure 1.

Figure 1: Using external CI/CD tool with AWS

Figure 1: Using external CI/CD tool with AWS

To make this deployment securely, the main objective is to use short-term credentials and avoid the need to generate and store long-term credentials for your pipelines. This post walks through how to use IAM Roles Anywhere and certificate-based authentication with Azure DevOps build agents. The walkthrough will use Azure DevOps Services with Microsoft-hosted agents. This approach can be used with a self-hosted agent or Azure DevOps Server.

IAM Roles Anywhere and certificate-based authentication

IAM Roles Anywhere uses a private certificate authority (CA) for the temporary security credential issuance process. Your private CA is registered with IAM Roles Anywhere through a service-to-service trust. Once the trust is established, you create an IAM role with an IAM policy that can be assumed by your services running outside of AWS. The external service uses a private CA issued X.509 certificate to request temporary AWS credentials from IAM Roles Anywhere and then assumes the IAM role with permission to finish the authentication process, as shown in Figure 2.

Figure 2: Certificate-based authentication for external CI/CD tool using IAM Roles Anywhere

Figure 2: Certificate-based authentication for external CI/CD tool using IAM Roles Anywhere

The workflow in Figure 2 is as follows:

  1. The external service uses its certificate to sign and issue a request to IAM Roles Anywhere.
  2. IAM Roles Anywhere validates the incoming signature and checks that the certificate was issued by a certificate authority configured as a trust anchor in the account.
  3. Temporary credentials are returned to the external service, which can then be used for other authenticated calls to the AWS APIs.

Walkthrough

In this walkthrough, you accomplish the following steps:

  1. Deploy IAM roles in your workload accounts.
  2. Create a root certificate to simulate your certificate authority. Then request and sign a leaf certificate to distribute to your build agent.
  3. Configure an IAM Roles Anywhere trust anchor in your workload accounts.
  4. Configure your pipelines to use certificate-based authentication with a working example using Azure DevOps pipelines.

Preparation

You can find the sample code for this post in our GitHub repository. We recommend that you locally clone a copy of this repository. This repository includes the following files:

  • DynamoDB_Table.template: This template creates an Amazon DynamoDB table.
  • iamra-trust-policy.json: This trust policy allows the IAM Roles Anywhere service to assume the role and defines the permissions to be granted.
  • parameters.json: This passes parameters when launching the CloudFormation template.
  • pipeline-iamra.yml: The definition of the pipeline that deploys the CloudFormation template using IAM Roles Anywhere authentication.
  • pipeline-iamra-multi.yml: The definition of the pipeline that deploys the CloudFormation template using IAM Roles Anywhere authentication in multi-account environment.

The first step is creating an IAM role in your AWS accounts with the necessary permissions to deploy your resources. For this, you create a role using the AWSCloudFormationFullAccess and AmazonDynamoDBFullAccess managed policies.

When you define the permissions for your actual applications and workloads, make sure to adjust the permissions to meet your specific needs based on the principle of least privilege.

Run the following command to create the CICDRole in the Dev and Prod AWS accounts.

aws iam create-role --role-name CICDRole --assume-role-policy-document file://iamra-trust-policy.json
aws iam attach-role-policy --role-name CICDRole --policy-arn arn:aws:iam::aws:policy/AmazonDynamoDBFullAccess
aws iam attach-role-policy --role-name CICDRole --policy-arn arn:aws:iam::aws:policy/AWSCloudFormationFullAccess

As part of the role creation, you need to apply the trust policy provided in iamra-trust-policy.json. This trust policy allows the IAM Roles Anywhere service to assume the role with the condition that the Subject Common Name (CN) of the certificate is cicdagent.example.com. In a later step you will update this trust policy with the Amazon Resource Name (ARN) of your trust anchor to further restrict how the role can be assumed.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Principal": {
                "Service": "rolesanywhere.amazonaws.com"
            },
            "Action": [
                "sts:AssumeRole",
                "sts:TagSession",
                "sts:SetSourceIdentity"
            ],
            "Condition": {
                "StringEquals": {
                    "aws:PrincipalTag/x509Subject/CN": "cicd-agent.example.com"
                }
            }
        }
    ]
}

Issue and sign a self-signed certificate

Use OpenSSL to generate and sign the certificate. Run the following commands to generate a root and leaf certificate.

Note: The following procedure has been tested with OpenSSL 1.1.1 and OpenSSL 3.0.8.

# generate key for CA certificate
openssl genrsa -out ca.key 2048

# generate CA certificate
openssl req -new -x509 -days 1826 -key ca.key -subj /CN=ca.example.com \
    -addext 'keyUsage=critical,keyCertSign,cRLSign,digitalSignature' \
    -addext 'basicConstraints=critical,CA:TRUE' -out ca.crt 

#generate key for leaf certificate
openssl genrsa -out private.key 2048

#request leaf certificate
cat > extensions.cnf <<EOF
[v3_ca]
keyUsage = digitalSignature, nonRepudiation, keyEncipherment, dataEncipherment
EOF

openssl req -new -key private.key -subj /CN=cicd-agent.example.com -out iamra-cert.csr

#sign leaf certificate with CA
openssl x509 -req -days 7 -in iamra-cert.csr -CA ca.crt -CAkey ca.key -set_serial 01 -extfile extensions.cnf -extensions v3_ca -out certificate.crt

The following files are needed in further steps: ca.crt, certificate.crt, private.key.

Configure the IAM Roles Anywhere trust anchor and profile in your workload accounts

In this step, you configure the IAM Roles Anywhere trust anchor, the profile, and the role with the associated IAM policy to define the permissions to be granted to your build agents. Make sure to set the permissions specified in the policy to the least privileged access.

To configure the IAM Role Anywhere trust anchor

  1. Open the IAM console and go to Roles Anywhere.
  2. Choose Create a trust anchor.
  3. Choose External certificate bundle and paste the content of your CA public certificate in the certificate bundle box (the content of the ca.crt file from the previous step). The configuration looks as follows:
Figure 3: IAM Roles Anywhere trust anchor

Figure 3: IAM Roles Anywhere trust anchor

To follow security best practices by applying least privilege access, add a condition statement in the IAM role’s trust policy to match the created trust anchor to make sure that only certificates that you want to assume a role through IAM Roles Anywhere can do so.

To update the trust policy of the created CICDRole

  1. Open the IAM console, select Roles, then search for CICDRole.
  2. Open CICDRole to update its configuration, and then select Trust relationships.
  3. Replace the existing policy with the following updated policy that includes an additional condition to match on the trust anchor. Replace the ARN ID in the policy with the ARN of the trust anchor created in your account.
Figure 4: IAM Roles Anywhere updated trust policy

Figure 4: IAM Roles Anywhere updated trust policy

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Principal": {
                "Service": "rolesanywhere.amazonaws.com"
            },
            "Action": [
                "sts:AssumeRole",
                "sts:TagSession",
                "sts:SetSourceIdentity"
            ],
            "Condition": {
                "StringEquals": {
                    "aws:PrincipalTag/x509Subject/CN": "cicd-agent.example.com"
                },
                "ArnEquals": {
                    "aws:SourceArn": "arn:aws:rolesanywhere:ca-central-1:111111111111:trust-anchor/9f084b8b-2a32-47f6-aee3-d027f5c4b03b"
                }
            }
        }
    ]
}

To create an IAM Role Anywhere profile and link the profile to CICDRole

  1. Open the IAM console and go to Roles Anywhere.
  2. Choose Create a profile.
  3. In the Profile section, enter a name.
  4. In the Roles section, select CICDRole.
  5. Keep the other options set to default.
Figure 5: IAM Roles Anywhere profile

Figure 5: IAM Roles Anywhere profile

Configure the Azure DevOps pipeline to use certificate-based authentication

Now that you’ve completed the necessary setup in AWS, you move to the configuration of your pipeline in Azure DevOps. You need to have access to an Azure DevOps organization to complete these steps.

Have the following values ready. They’re needed for the Azure DevOps Pipeline configuration. You need this set of information for every AWS account you want to deploy to.

  • Trust anchor ARN – Resource identifier for the trust anchor created when you configured IAM Roles Anywhere.
  • Profile ARN – The identifier of the IAM Roles Anywhere profile you created.
  • Role ARN – The ARN of the role to assume. This role needs to be configured in the profile.
  • Certificate – The certificate tied to the profile (in other words, the issued certificate: file certificate.crt).
  • Private key – The private key of the certificate (private.key).

Azure DevOps configuration steps

The following steps walk you through configuring Azure DevOps.

  1. Create a new project in Azure DevOps.
  2. Add the following files from the sample repository that you previously cloned to the Git Azure repo that was created as part of the project. (The simplest way to do this is to add a new remote to your local Git repository and push the files.)
    • DynamoDB_Table.template – The sample CloudFormation template you will deploy
    • parameters.json – This passes parameters when launching the CloudFormation template
    • pipeline-iamra.yml – The definition of the pipeline that deploys the CloudFormation template using IAM RA authentication
  3. Create a new pipeline:
    1. Select Azure Repos Git as your source.
    2. Select your current repository.
    3. Choose Existing Azure Pipelines YAML file.
    4. For the path, enter pipeline-iamra.yml.
    5. Select Save (don’t run the pipeline yet).
  4. In Azure DevOps, choose Pipelines, and then choose Library.
  5. Create a new variable group called aws-dev that will store the configuration values to deploy to your AWS Dev environment.
  6. Add variables corresponding to the values of the trust anchor profile and role to use for authentication.
    Figure 6: Azure DevOps configuration steps: Adding IAM Roles Anywhere variables

    Figure 6: Azure DevOps configuration steps: Adding IAM Roles Anywhere variables

  7. Save the group.
  8. Update the permissions to allow your pipeline to use the variable group.
    Figure 7: Azure DevOps configuration steps: Pipeline permissions

    Figure 7: Azure DevOps configuration steps: Pipeline permissions

  9. In the Library, choose the Secure files tab to upload the certificate and private key files that you generated previously.
    Figure 8: Azure DevOps configuration steps: Upload certificate and private key

    Figure 8: Azure DevOps configuration steps: Upload certificate and private key

  10. For each file, update the Pipeline permissions to provide access to the pipeline created previously.
    Figure 9: Azure DevOps configuration steps: Pipeline permissions for each file

    Figure 9: Azure DevOps configuration steps: Pipeline permissions for each file

  11. Run the pipeline and validate successful completion. In your AWS account, you should see a stack named my-stack-name that deployed a DynamoDB table.
    Figure 10: Verify CloudFormation stack deployment in your account

    Figure 10: Verify CloudFormation stack deployment in your account

Explanation of the pipeline-iamra.yml

Here are the different steps of the pipeline:

  1. The first step downloads and installs the credential helper tool that allows you to obtain temporary credentials from IAM Roles Anywhere.
    - bash: wget https://rolesanywhere.amazonaws.com/releases/1.0.3/X86_64/Linux/aws_signing_helper; chmod +x aws_signing_helper;
      displayName: Install AWS Signer

  2. The second step uses the DownloadSecureFile built-in task to retrieve the certificate and private key that you stored in the Azure DevOps secure storage.
    - task: DownloadSecureFile@1
      name: Certificate
      displayName: 'Download certificate'
      inputs:
        secureFile: 'certificate.crt'
    
    - task: DownloadSecureFile@1
      name: Privatekey
      displayName: 'Download private key'
      inputs:
        secureFile: 'private.key'

    The credential helper is configured to obtain temporary credentials by providing the certificate and private key as well as the role to assume and an IAM AWS Roles Anywhere profile to use. Every time the AWS CLI or AWS SDK needs to authenticate to AWS, they use this credential helper to obtain temporary credentials.

    bash: |
        aws configure set credential_process "./aws_signing_helper credential-process --certificate $(Certificate.secureFilePath) --private-key $(Privatekey.secureFilePath) --trust-anchor-arn $(TRUSTANCHORARN) --profile-arn $(PROFILEARN) --role-arn $(ROLEARN)" --profile default
        echo "##vso[task.setvariable variable=AWS_SDK_LOAD_CONFIG;]1"
      displayName: Obtain AWS Credentials

  3. The next step is for troubleshooting purposes. The AWS CLI is used to confirm the current assumed identity in your target AWS account.
    task: AWSCLI@1
      displayName: Check AWS identity
      inputs:
        regionName: 'ca-central-1'
        awsCommand: 'sts'
        awsSubCommand: 'get-caller-identity'

  4. The final step uses the CloudFormationCreateOrUpdateStack task from the AWS Toolkit for Azure DevOps to deploy the Cloud Formation stack. Usually, the awsCredentials parameter is used to point the task to the Service Connection with the AWS access keys and secrets. If you omit this parameter, the task looks instead for the credentials in the standard credential provider chain.
    task: CloudFormationCreateOrUpdateStack@1
      displayName: 'Create/Update Stack: Staging-Deployment'
      inputs:
        regionName:     'ca-central-1'
        stackName:      'my-stack-name'
        useChangeSet:   true
        changeSetName:  'my-stack-name-changeset'
        templateFile:   'DynamoDB_Table.template'
        templateParametersFile: 'parameters.json'
        captureStackOutputs: asVariables
        captureAsSecuredVars: false

Multi-account deployments

In this example, the pipeline deploys to a single AWS account. You can quickly extend it to support deployment to multiple accounts by following these steps:

  1. Repeat the Configure IAM Roles Anywhere Trust Anchor for each account.
  2. In Azure DevOps, create a variable group with the configuration specific to the additional account.
  3. In the pipeline definition, add a stage that uses this variable group.

The pipeline-iamra-multi.yml file in the sample repository contains such an example.

Cleanup

To clean up the AWS resources created in this article, follow these steps:

  1. Delete the deployed CloudFormation stack in your workload accounts.
  2. Remove the IAM trust anchor and profile from the workload accounts.
  3. Delete the CICDRole IAM role.

Alternative options available to obtain temporary credentials in AWS for CI/CD pipelines

In addition to the IAM Roles Anywhere option presented in this blog, there are two other options to issue temporary security credentials for the external build agent:

  • Option 1 – Re-host the build agent on an Amazon Elastic Compute Cloud (Amazon EC2) instance in the AWS account and assign an IAM role. (See IAM roles for Amazon EC2). This option resolves the issue of using long-term IAM access keys to deploy self-hosted build agents on an AWS compute service (such as Amazon EC2, AWS Fargate, or Amazon Elastic Kubernetes Service (Amazon EKS)) instead of using fully-managed or on-premises agents, but it would still require using multiple agents for pipelines that need different permissions.
  • Option 2 – Some DevOps tools support the use of OpenID Connect (OIDC). OIDC is an authentication layer based on open standards that makes it simpler for a client and an identity provider to exchange information. CI/CD tools such as GitHub, GitLab, and Bitbucket provide support for OIDC, which helps you to integrate with AWS for secure deployments and resources access without having to store credentials as long-lived secrets. However, not all CI/CD pipeline tools supports OIDC.

Conclusion

In this post, we showed you how to combine IAM Roles Anywhere and an existing public key infrastructure (PKI) to authenticate external build agents to AWS by using short-lived certificates to obtain AWS temporary credentials. We presented the use of Azure Pipelines for the demonstration, but you can adapt the same steps to other CI/CD tools running on premises or in other cloud platforms. For simplicity, the certificate was manually configured in Azure DevOps to be provided to the agents. We encourage you to automate the distribution of short-lived certificates based on an integration with your PKI.

For demonstration purposes, we included the steps of generating a root certificate and manually signing the leaf certificate. For production workloads, you should have access to a private certificate authority to generate certificates for use by your external build agent. If you do not have an existing private certificate authority, consider using AWS Private Certificate Authority.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Security, Identity, & Compliance re:Post or contact AWS Support.
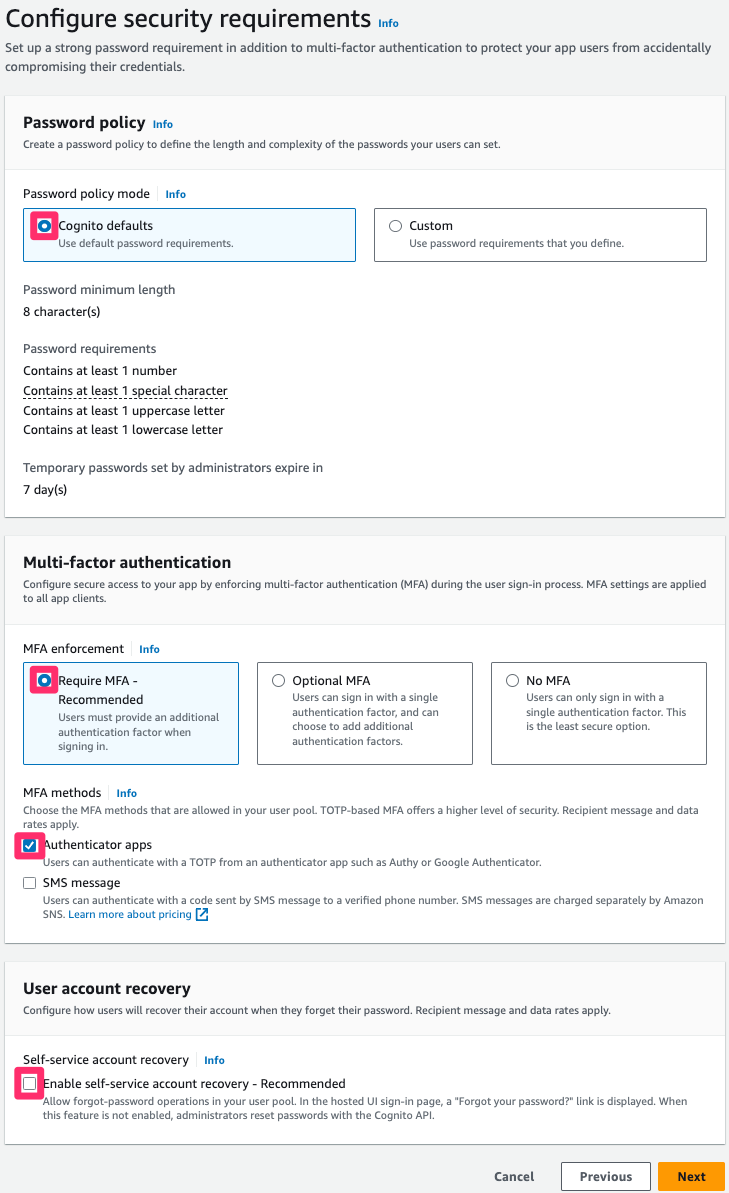
Want more AWS Security news? Follow us on Twitter.

Olivier Gaumond

Olivier Gaumond

Olivier is a Senior Solutions Architect supporting public sector customers from Quebec City. His varied experience in consulting, application development, and platform implementation allow him to bring a new perspective to projects. DevSecOps, containers, and cloud native development are among his topics of interest.

Manal Taki

Manal Taki

Manal is a solutions Architect at AWS, based in Toronto. She works with public sector customers to solve business challenges to drive their mission goals by using Amazon Web Services (AWS). She’s passionate about security, and works with customers to enable security best practices to build secure environments and workloads in the cloud.

Explore visualizations with AWS Glue interactive sessions

Post Syndicated from Annie Nelson original https://aws.amazon.com/blogs/big-data/explore-visualizations-with-aws-glue-interactive-sessions/

AWS Glue interactive sessions offer a powerful way to iteratively explore datasets and fine-tune transformations using Jupyter-compatible notebooks. Interactive sessions enable you to work with a choice of popular integrated development environments (IDEs) in your local environment or with AWS Glue or Amazon SageMaker Studio notebooks on the AWS Management Console, all while seamlessly harnessing the power of a scalable, on-demand Apache Spark backend. This post is part of a series exploring the features of AWS Glue interactive sessions.

AWS Glue interactive sessions now include native support for the matplotlib visualization library (AWS Glue version 3.0 and later). In this post, we look at how we can use matplotlib and Seaborn to explore and visualize data using AWS Glue interactive sessions, facilitating rapid insights without complex infrastructure setup.

Solution overview

You can quickly provision new interactive sessions directly from your notebook without needing to interact with the AWS Command Line Interface (AWS CLI) or the console. You can use magic commands to provide configuration options for your session and install any additional Python modules that are needed.

In this post, we use the classic Iris and MNIST datasets to navigate through a few commonly used visualization techniques using matplotlib on AWS Glue interactive sessions.

Create visualizations using AWS Glue interactive sessions

We start by installing the Sklearn and Seaborn libraries using the additional_python_modules Jupyter magic command:

%additional_python_modules scikit-learn, seaborn

You can also upload Python wheel modules to Amazon Simple Storage Service (Amazon S3) and specify the full path as a parameter value to the additional_python_modules magic command.

Now, let’s run a few visualizations on the Iris and MNIST datasets.

  1. Create a pair plot using Seaborn to uncover patterns within sepal and petal measurements across the iris species:
    import seaborn as sns
    import matplotlib.pyplot as plt
    
    # Load the Iris dataset
    iris = sns.load_dataset("iris")
    
    # Create a pair plot
    sns.pairplot(iris, hue="species")
    %matplot plt

  2. Create a violin plot to reveal the distribution of the sepal width measure across the three species of iris flowers:
    # Create a violin plot of the Sepal Width measure
    plt.figure(figsize=(10, 6))
    sns.violinplot(x="species", y="sepal_width", data=iris)
    plt.title("Violin Plot of Sepal Width by Species")
    plt.show()
    %matplot plt

  3. Create a heat map to display correlations across the iris dataset variables:
    # Calculate the correlation matrix
    correlation_matrix = iris.corr()
    
    # Create a heatmap using Seaborn
    plt.figure(figsize=(8, 6))
    sns.heatmap(correlation_matrix, annot=True, cmap="coolwarm")
    plt.title("Correlation Heatmap")
    %matplot plt

  4. Create a scatter plot on the MNIST dataset using PCA to visualize distributions among the handwritten digits:
    import matplotlib.pyplot as plt
    from sklearn.datasets import fetch_openml
    from sklearn.decomposition import PCA
    
    # Load the MNIST dataset
    mnist = fetch_openml('mnist_784', version=1)
    X, y = mnist['data'], mnist['target']
    
    # Apply PCA to reduce dimensions to 2 for visualization
    pca = PCA(n_components=2)
    X_pca = pca.fit_transform(X)
    
    # Scatter plot of the reduced data
    plt.scatter(X_pca[:, 0], X_pca[:, 1], c=y.astype(int), cmap='viridis', s=5)
    plt.xlabel("Principal Component 1")
    plt.ylabel("Principal Component 2")
    plt.title("PCA - MNIST Dataset")
    plt.colorbar(label="Digit Class")
    
    %matplot plt

  5. Create another visualization using matplotlib and the mplot3d toolkit:
    import numpy as np
    import matplotlib.pyplot as plt
    from mpl_toolkits.mplot3d import Axes3D
    
    # Generate mock data
    x = np.linspace(-5, 5, 100)
    y = np.linspace(-5, 5, 100)
    x, y = np.meshgrid(x, y)
    z = np.sin(np.sqrt(x**2 + y**2))
    
    # Create a 3D plot
    fig = plt.figure(figsize=(10, 8))
    ax = fig.add_subplot(111, projection='3d')
    
    # Plot the surface
    surface = ax.plot_surface(x, y, z, cmap='viridis')
    
    # Add color bar to map values to colors
    fig.colorbar(surface, ax=ax, shrink=0.5, aspect=10)
    
    # Set labels and title
    ax.set_xlabel('X')
    ax.set_ylabel('Y')
    ax.set_zlabel('Z')
    ax.set_title('3D Surface Plot Example')
    
    %matplot plt

As illustrated by the preceding examples, you can use any compatible visualization library by installing the required modules and then using the %matplot magic command.

Conclusion

In this post, we discussed how extract, transform, and load (ETL) developers and data scientists can efficiently visualize patterns in their data using familiar libraries through AWS Glue interactive sessions. With this functionality, you’re empowered to focus on extracting valuable insights from their data, while AWS Glue handles the infrastructure heavy lifting using a serverless compute model. To get started today, refer to Developing AWS Glue jobs with Notebooks and Interactive sessions.


About the authors

Annie Nelson is a Senior Solutions Architect at AWS. She is a data enthusiast who enjoys problem solving and tackling complex architectural challenges with customers.

Keerthi Chadalavada is a Senior Software Development Engineer at AWS Glue. She is passionate about designing and building end-to-end solutions to address customer data integration and analytic needs.
Zach Mitchell is a Sr. Big Data Architect. He works within the product team to enhance understanding between product engineers and their customers while guiding customers through their journey to develop their enterprise data architecture on AWS.
Gal blog picGal Heyne is a Product Manager for AWS Glue with a strong focus on AI/ML, data engineering and BI. She is passionate about developing a deep understanding of customer’s business needs and collaborating with engineers to design easy to use data products.