As organizations migrate more mission-critical workloads to the cloud, optimizing for price-performance becomes a key consideration. Amazon Elastic Compute Cloud (Amazon EC2) instances powered by AMD EPYC processors deliver high core density, large memory bandwidth, and hardware-enabled security features, making them a strong option for a wide range of compute, memory, and I/O-intensive workloads. In this post, we explain how to choose the right AMD-based Amazon EC2 instance types and describe tuning techniques that can help users improve workload efficiency. Whether you’re running simulations, large-scale analytics, or inference workloads, this post provides practical guidance for optimizing AMD-powered Amazon EC2 instance.
Amazon EC2 offers AMD-based instances built on multiple generations of AMD EPYC processors. This post focuses on optimization strategies for the 3rd and 4th generation families, which provide enhanced capabilities for compute and memory-intensive workloads.
3rd generation (M6a, R6a, C6a, Hpc6a): Balances compute, memory, and storage—well-suited for analytics, web servers, and high-performance computing.
4th generation (M7a, R7a, C7a, Hpc7a): Deliver up to 50% better performance over earlier AMD generations These instances introduce AVX-512 support, DDR5 memory, and Simultaneous Multithreading (SMT) turned off, SMT is a technology that allows a single physical core to run multiple threads concurrently; with SMT disabled, each virtual CPU (vCPU) maps directly to a physical core, which can improve workload isolation and consistency.
Choosing the right AMD EPYC powered Amazon EC2 instance type
Selecting the right AMD EPYC powered Amazon EC2 instance type starts with understanding how your application uses compute, memory, storage, and networking resources. Each instance family is optimized for specific workload characteristics.
Compute-intensive workloads
These workloads involve large-scale calculations, simulations, or encoding tasks, and they often need high CPU throughput and advanced instruction set support.
Recommended instances: C7a, Hpc7a, C6a, Hpc6a Use cases: Scientific computing, financial modelling, media transcoding, encryption, machine learning (ML) inference
Big data and analytics
Applications that process and analyze large datasets benefit from high memory bandwidth and a balanced compute-to-memory ratio.
Recommended instances: R7a, M7a, R6a, M6a Use cases: Stream processing, real-time analytics, business intelligence tools, distributed caching
Database workloads
Database workloads typically need consistent memory performance and high I/O throughput for read/write operations.
Aligning your instance type with the needs of your workload helps provide predictable performance and cost efficiency. Services such as Amazon EC2 Auto Scaling and AWS Compute Optimizer can assist with ongoing instance selection and scaling decisions.
Optimizing AMD EPYC powered Amazon EC2 instances
Amazon EC2 instances powered by 4th generation AMD EPYC processors use a modular chiplet architecture, as shown in the following figure. Each processor includes multiple Core Complex Dies (CCDs), and each CCD contains one or more core complexes (CCXs). A CCX groups up to eight physical cores, with each core having 1 MB of dedicated L2 cache and all eight cores sharing a 32 MB L3 cache. These CCDs are connected to a central I/O die, which manages memory and interconnects across the chip.
Figure 1: Layout of the ‘Zen 4’ CPU die with 8 cores per die
The modular architecture of 4th generation AMD EPYC processors enables Amazon EC2 instances such as m7a.24xlarge and m7a.48xlarge to support high core counts-up to 96 physical cores per socket. For example:
m7a.24xlarge provides 96 physical cores from a single socket.
m7a.48xlarge spans two sockets, offering 192 physical cores.
Understanding how Amazon EC2 instance sizes map to physical processor layouts can help you optimize for performance and cache locality. Workloads that involve shared memory access or thread synchronization, such as high-performance computing or in-memory databases, can benefit from selecting instance sizes that minimize cross-socket communication and make efficient use of shared L3 cache, as shown in the following figure.
Figure 2: Layout of the ‘EPYC Chiplet’ CPU
Amazon EC2 instances powered by 4th generation AMD EPYC processors operate with SMT turned off. In this configuration, each vCPU maps directly to a physical core, eliminating resource sharing such as execution units and cache between sibling threads. This design can reduce intra-core interference and help provide more consistent performance under certain workloads. Users can isolate threads at the core level and observe lower variability and more stable throughput for workloads, such as high-performance computing, ML inference, and transactional databases.
CPU optimizations
Tools such as htop can help identify CPU usage patterns, system load averages, and per-process resource consumption. CPU usage should be evaluated in the context of your workload and performance requirements. If usage consistently reaches 100%, then it may indicate that the workload is CPU-bound and not optimally balanced. Before modifying the instance size, enabling Auto Scaling, or switching instance families, evaluations must be conducted for the tuning opportunities that could improve performance without changing infrastructure. Load averages that regularly exceed the number of vCPUs can also signal compute saturation and may warrant further optimization.
L3 cache usage
The L3 cache is a shared, high-speed memory layer used by a group of CPU cores. On AMD-based Amazon EC2, cores are organized into L3 cache slices, each shared by a subset of cores on the same socket. Threads scheduled within the same slice can access shared data more efficiently, reducing memory latency. On 4th generation AMD instances such as m7a.2xlarge or r7a.2xlarge, all vCPUs typically map to cores within a single L3 slice, which ensures consistent cache locality. For larger sizes (for example m7a.8xlarge and above), thread pinning—assigning threads to specific physical cores—can help maintain this locality. Thread pinning can reduce performance variability in workloads with shared-memory access patterns.
You can pin threads using the taskset command:
taskset -c 0-3 ./your_application
This example pins your application to CPU cores 0 through 3. To determine which cores share the same L3 cache region, use tools such as lscpu or lstopo to inspect the system’s CPU topology. Grouping related threads on cores that share an L3 cache can improve performance consistency for workloads with frequent shared-memory access.
Docker container optimization
In containerized environments running on AMD-based Amazon EC2 instances, tuning CPU-related settings can improve workload consistency and efficiency—particularly for compute-intensive or latency-sensitive applications. Although default configurations work for many general-purpose scenarios, certain workloads may benefit from more explicit control over how CPU resources are allocated. By default, container runtimes such as Docker allow the operating system to schedule containers across any available CPU cores. This flexible scheduling can lead to variability in performance when containers move across cores that don’t share cache. To reduce this variability and improve cache efficiency, containers can be pinned to specific cores using the --cpuset-cpus flag.
docker run --cpuset-cpus="1,3" my-container
This setting restricts the container to use only the specified cores. In this example, cores 1 and 3 are used for demonstration. The actual core selection should be based on CPU topology to make sure of cache-efficient scheduling. Pinning containers to cores that share L3 cache can reduce scheduling overhead and improve consistency for workloads with shared-memory access patterns.
CPU frequency governor settings
Some operating systems adjust CPU frequency dynamically to save power. This is typically controlled by a setting called the CPU frequency governor. Although this behavior is efficient for general-purpose workloads, it may introduce latency or performance variability in compute-sensitive environments. For workloads that need consistently high CPU performance—such as high-throughput data processing, simulations, or real-time applications—we recommend setting the CPU governor to performance mode. This makes sure that the CPU runs at its maximum frequency under load, avoiding time spent ramping up from lower power states.
You can apply this setting on bare metal instances or Amazon EC2 Dedicated Hosts using the following command:
sudo cpupower frequency-set -g performance
Before applying, consider benchmarking workload performance with other CPU frequency governors (such as ondemand or schedutil) to make sure that the performance setting provides measurable benefits without unnecessary energy trade-offs.
Use architecture-specific compiler flags
When compiling performance-sensitive C or C++ applications, architecture-specific flags such as -march=znverX can unlock AMD EPYC–specific optimizations, including improved vectorization and floating-point performance. Although this is beneficial for compute-heavy workloads, it may reduce portability across architectures. To balance performance and flexibility, consider implementing runtime feature detection and dispatching an approach used by many optimized libraries to adapt behavior based on the underlying CPU.
Before using these flags, verify that your compiler version supports them and make sure that the target EC2 instance architecture matches the specified flag. For example, a binary compiled with -march=znver4 may fail with an illegal instruction error (SIGILL) if run on earlier-generation instances such as M5a.The following table outlines the appropriate flags and minimum supported compiler versions for each AMD EPYC generation:
AMD EPYC Generation
-march Flag
Minimum GCC Version
Minimum LLVM/Clang Version
4th generation (for example M7a)
znver4
GCC 12
Clang 15
3rd generation (for example M6a)
znver3
GCC 11
Clang 13
2nd generation (for example M5a)
znver2
GCC 9
Clang 11
The following flags are supported for GCC 11+ or LLVM Clang 13+:
# 4th Gen EPYC (M7a, R7a, C7a, Hpc7a)
-march=znver4

# 3rd Gen EPYC (M6a, R6a, C6a)
-march=znver3

# 2nd Gen EPYC (M5a, R5a, C5a)
-march=znver2
When to enable AVX-512 and VNNI instructions
4th generation AMD EPYC powered Amazon EC2 instances support advanced single instruction, multiple data (SIMD) instruction sets such as AVX2, AVX-512, and VNNI. These can improve throughput for vector-heavy workloads such as ML inference, image processing, or scientific simulations. However, these flags are generation-specific—attempting to run binaries compiled with AVX-512 on unsupported instances (for example 2nd generation M5a) may result in runtime errors such as illegal instruction (SIGILL).
To better understand which optimizations are applied, use the following:
-ftree-vectorizer-verbose=2 -fopt-info-vec-missed
This helps identify loops that benefit from vectorization and those that don’t. Only enable these optimizations if your workload benefits and you’ve validated compatibility with the instance generation in use. Avoid applying AVX flags indiscriminately, because it may reduce portability and increase binary complexity.
AMD Optimizing CPU Libraries
The AMD Optimizing CPU Libraries (AOCL) provide performance-tuned math libraries specifically designed for AMD EPYC processors. These libraries include optimized implementations of commonly used functions in scientific computing, engineering, and ML workloads. You can link your applications against AOCL to use processor-specific optimizations without rewriting your code. AOCL includes libraries for vector and scalar math, random number generation, FFT, BLAS, and LAPACK, among others.
Setting up AOCL
Set the AOCL_ROOT environment variable to point to the installation directory:
export AOCL_ROOT=/path/to/aocl
Compile your application with the appropriate include and library paths:
AOCL runtime profiling: AOCL supports runtime profiling, which helps developers identify which mathematical operations dominate execution time. To enable profiling, run the following:
export AOCL_PROFILE=1
./your_program
After running this, a report file named aocl_profile_report.txt is generated. It provides a function-level breakdown of call counts, execution time, and thread usage. Developers can use this to focus optimization efforts on high-impact operations.
Conclusion
This post explored how to select AMD-based Amazon EC2 instance types that align with specific workload characteristics, and how to apply tuning techniques focused on CPU usage, thread placement, cache efficiency, and math library optimization. These approaches are especially relevant for compute-bound or latency-sensitive workloads where consistent performance is critical.
Ready to get started? Sign in to the AWS Management Console and launch AMD EPYC powered Amazon EC2 instances to begin optimizing your workloads today.
In Part 1 of this series, we discussed fundamental operations to control the lifecycle of your Amazon Managed Service for Apache Flink application. If you are using higher-level tools such as AWS CloudFormation or Terraform, the tool will execute these operations for you. However, understanding the fundamental operations and what the service automatically does can provide some level of Mechanical Sympathy to confidently implement a more robust automation.
In the first part of this series, we focused on the happy paths. In an ideal world, failures don’t happen, and every change you deploy works perfectly. However, the real world is less predictable. Quoting Werner Vogels, Amazon’s CTO, “Everything fails, all the time.”
In this post, we explore failure scenarios that can happen during normal operations or when you deploy a change or scale the application, and how to monitor operations to detect and recover when something goes wrong.
The less happy path
A robust automation must be designed to handle failure scenarios, in particular during operations. To do that, we need to understand how Apache Flink can deviate from the happy path. Due to the nature of Flink as a stateful stream processing engine, detecting and resolving failure scenarios requires different techniques compared to other long-running applications, such as microservices or short-lived serverless functions (such as AWS Lambda).
Flink’s behavior on runtime errors: The fail-and-restart loop
When a Flink job encounters an unexpected error at runtime (an unhandled exception), the normal behavior is to fail, stop the processing, and restart from the latest checkpoint. Checkpoints allow Flink to support data consistency and no data loss in case of failure. Also, because Flink is designed for stream processing applications, which run continuously, if the error happens again, the default behavior is to keep restarting, hoping the problem is transient and the application will eventually recover the normal processing.In some cases, the problem is not transient, however. For example, when you deploy a code change that contains a bug, causing the job to fail as soon as it starts processing data, or if the expected schema doesn’t match the records in the source, causing deserialization or processing errors. The same scenario might also happen if you mistakenly changed a configuration that prevents a connector to reach the external system. In these cases, the job is stuck in a fail-and-restart loop, indefinitely, or until you actively force-stop it.
When this happens, the Managed Service for Apache Flink application status might be RUNNING, but the underlying Flink job is actually failing and restarting. The AWS Management Console gives you a hint, pointing that the application might need attention (see the following screenshot).
In the following sections, we learn how to monitor the application and job status, to automatically react to this situation.
When starting or updating the application goes wrong
To understand the failure mode, let’s review what happens automatically when you start the application, or when the application restarts after you issued UpdateApplication command, as we explored in Part 1 of this series. The following diagram illustrates what happens when an application starts.
The workflow consists of the following steps:
Managed Service for Apache Flink provisions a cluster dedicated to your application.
The code and configuration are submitted to the Job Manager node.
The code in the main() method of your application runs, defining the dataflow of your application.
Flink deploys to the Task Manager nodes the substasks that make up your job.
The job and application status change to RUNNING. However, subtasks start initializing now.
Subtasks restore their state, if applicable, and initialize any resources. For example, a Kafka connector’s subtask initializes the Kafka client and subscribes the topic.
When all subtasks are successfully initialized, they change to RUNNING status and the job starts processing data.
To new Flink users, it can be confusing that a RUNNING status doesn’t necessarily imply the job is healthy and processing data.When something goes wrong during the process of starting (or restarting) the application, depending on the phase when the problem arises, you might observe two different types of failure modes:
(a) A problem prevents the application code from being deployed – Your application might encounter this failure scenario if the deployment fails as soon as the code and configuration are passed to the Job Manager (step 2 of the process), for example if the application code package is malformed. A typical error is when the JAR is missing a mainClass or if mainClass points to a class that doesn’t exist. This failure mode might also happen if the code of your main() method throws an unhandled exception (step 3). In these cases, the application fails to change to RUNNING, and reverts to READY after the attempt.
(b) The application is started, the job is stuck in a fail-and-restart loop – A problem might occur later in the process, after the application status has changed RUNNING. For example, after the Flink job has been deployed to the cluster (step 4 of the process), a component might fail to initialize (step 6). This might happen when a connector is misconfigured, or a problem prevents it from connecting to the external system. For example, a Kafka connector might fail to connect to the Kafka cluster because of the connector’s misconfiguration or networking issues. Another possible scenario is when the Flink job successfully initializes, but it throws an exception as soon as it starts processing data (step 7). When this happens, Flink reacts to a runtime error and might get stuck in a fail-and-restart loop.
The following diagram illustrates the sequence of application status, including the two failure scenarios just described.
Troubleshooting
We have examined what can go wrong during operations, in particular when you update a RUNNING application or restart an application after changing its configuration. In this section, we explore how we can act on these failure scenarios.
Roll back a change
When you deploy a change and realize something is not quite right, you normally want to roll back the change and put the application back in working order, until you investigate and fix the problem. Managed Service for Apache Flink provides a graceful way to revert (roll back) a change, also restarting the processing from the point it was stopped before applying the fault change, providing consistency and no data loss.In Managed Service for Apache Flink, there are two types of rollbacks:
Automatic – During an automatic rollback (also called system rollback), if enabled, the service automatically detects when the application fails to restart after a change, or when the job starts but immediately falls into a fail-and-restart loop. In these situations, the rollback process automatically restores the application configuration version before the last change was applied and restarts the application from the snapshot taken when the change was deployed. See Improve the resilience of Amazon Managed Service for Apache Flink application with system-rollback feature for more details. This feature is disabled by default. You can enable it as part of the application configuration.
Manual – A manual rollback API operation is like a system rollback, but it’s initiated by the user. If the application is running but you observe something not behaving as expected after applying a change, you can trigger the rollback operation using the RollbackApplication API action or the console. Manual rollback is possible when the application is RUNNING or UPDATING.
Both rollbacks work similarly, restoring the configuration version before the change and restarting with the snapshot taken before the change. This prevents data loss and brings you back to a version of the application that was working. Also, this uses the code package that was saved at the time you created the previous configuration version (the one you are rolling back to), so there is no inconsistency between code, configuration, and snapshot, even if in the meantime you have replaced or deleted the code package from the Amazon Simple Storage Service (Amazon S3) bucket.
Implicit rollback: Update with an older configuration
A third way to roll back a change is to simply update the configuration, bringing it back to what it was before the last change. This creates a new configuration version, and requires the correct version of the code package to be available in the S3 bucket when you issue the UpdateApplication command.
Why is there a third option when the service provides system rollback and the managed RollbackApplication action? Because most high-level infrastructure-as-code (IaC) frameworks such as Terraform use this strategy, explicitly overwriting the configuration. It is important to understand this possibility even though you will probably use the managed rollback if you implement your automation based on the low-level actions.
The following are two important caveats to consider for this implicit rollback:
You will normally want to restart the application from the snapshot that was taken before the faulty change was deployed. If the application is currently RUNNING and healthy, this is not the latest snapshot (RESTORE_FROM_LATEST_SNAPSHOT), but rather the previous one. You must set the restart from RESTORE_FROM_CUSTOM_SNAPSHOT and select the correct snapshot.
UpdateApplication only works if the application is RUNNING and healthy, and the job can be gracefully stopped with a snapshot. Conversely, if the application is stuck in a fail-and-restart loop, you must force-stop it first, change the configuration while the application is READY, and later start the application from the snapshot that was taken before the faulty change was deployed.
Force-stop the application
In normal scenarios, you stop the application gracefully, with the automatic snapshot creation. However, this might not be possible in some scenarios, such as if the Flink job is stuck in a fail-and-restart loop. This might happen, for example, if an external system the job uses stops working, or because the AWS Identity and Access Management (IAM) configuration was erroneously modified, removing permissions required by the job.
When the Flink job gets stuck in a fail-and-restart loop after a faulty change, your first option should be using RollbackApplication, which automatically restores the previous configuration and starts from the correct snapshot. In the rare cases you can’t stop the application gracefully or use RollbackApplication, the last resort is force-stopping the application. Force-stop uses the StopApplication command with Force=true. You can also force-stop the application from the console.
When you force-stop an application, no snapshot is taken (if that were possible, you would have been able to gracefully stop). When you restart the application, you can either skip restoring from a snapshot (SKIP_RESTORE_FROM_SNAPSHOT) or use a snapshot that was previously taken, scheduled using Snapshot Manager, or manually, using the console or CreateApplicationSnapshot API action.
We strongly recommend setting up scheduled snapshots for all production applications that you can’t afford restarting with no state.
Monitoring Apache Flink application operations
Effective monitoring of your Apache Flink applications during and after operations is crucial to verify the outcome of the operation and allow lifecycle automation to raise alarms or react, in case something goes wrong.
The main indicators you can use during operations include the FullRestarts metric (available in Amazon CloudWatch) and the application, job, and task status.
Monitoring the outcome of an operation
The simplest way to detect the outcome of an operation, such as StartApplication or UpdateApplication, is to use the ListApplicationOperations API command. This command returns a list of the most recent operations of a specific application, including maintenance events that force an application restart.
For example, to retrieve the status of the most recent operation, you can use the following command:
OperationStatus will follow the same logic as the application status reported by the console and by DescribeApplication. This means it might not detect a failure during the operator initialization or while the job starts processing data. As we have learned, these failures might put the application in a fail-and-restart loop. To detect these scenarios using your automation, you must use other techniques, which we cover in the rest of this section.
Detecting the fail-and-restart loop using the FullRestarts metric
The simplest way to detect whether the application is stuck in a fail-and-restart loop is using the fullRestarts metric, available in CloudWatch Metrics. This metric counts the number of restarts of the Flink job after you started the application with a StartApplication command or restarted with UpdateApplication.
In a healthy application, the number of full restarts should ideally be zero. A single full restart might be acceptable during deployment or planned maintenance; multiple restarts normally indicate some issue. We recommend not to trigger an alarm on a single restart, or even a couple of consecutive restarts.
The alarm should only be triggered when the application is stuck in a fail-and-restart loop. This implies checking whether several restarts have happened over a relatively short period of time. Deciding the period is not trivial, because the time the Flink job takes to restart from a checkpoint depends on the size of the application state. However, if the state of your application is lower than several GB per KPU, you can safely assume the application should start in less than a minute.
The goal is creating a CloudWatch alarm that triggers when fullRestarts keeps increasing over a time period sufficient for multiple restarts. For example, assuming your application restarts in less than 1 minute, you can create a CloudWatch alarm that relies on the DIFF math expression of the fullRestarts metric. The following screenshot shows an example of the alarm details.
This example is a conservative alarm, only triggering if the application keeps restarting for over 5 minutes. This means you detect the problem after at least 5 minutes. You might consider reducing the time to detect the failure earlier. However, be careful not to trigger an alarm after just one or two restarts. Occasional restarts might happen, for example during normal maintenance (patching) that is managed by the service, or for a transient error of an external system. Flink is designed to recover from these conditions with minimal downtime and no data loss.
Detecting whether the job is up and running: Monitoring application, job, and task status
We have discussed how you have different statuses: the status of the application, job, and subtask. In Managed Service for Apache Flink, the application and job status change to RUNNING when the subtasks are successfully deployed on the cluster. However, the job is not really running and processing data until all the subtasks are RUNNING.
Observing the application status during operations
The application status is visible on the console, as shown in the following screenshot.
In your automation, you can poll the DescribeApplication API action to observe the application status. The following command shows how to use the AWS Command Line Interface (AWS CLI) and jq command to extract the status string of an application:
Managed Service for Apache Flink gives you access to the Flink Dashboard, which provides useful information for troubleshooting, including the status of all subtasks. The following screenshot, for example, shows a healthy job where all subtasks are RUNNING.
In the following screenshot, we can see a job where subtasks are failing and restarting.
In your automation, when you start the application or deploy a change, you want to be sure the job is eventually up and running and processing data. This happens when all the subtasks are RUNNING. Note that waiting for the job status to become RUNNING after an operation is not completely safe. A subtask might still fail and cause the job to restart after it was reported as RUNNING.
After you execute a lifecycle operation, your automation can poll the substasks status waiting for one of two events:
All subtasks report RUNNING – This indicates the operation was successful and your Flink job is up and running.
Any subtask reports FAILING or CANCELED – This indicates something went wrong, and the application is likely stuck in a fail-and-restart loop. You need to intervene, for example, force-stopping the application and then rolling back the change.
If you are restarting from a snapshot and the state of your application is quite big, you might observe subtasks will report INITIALIZING status for longer. During the initialization, Flink restores the state of the operator before changing to RUNNING.
The Flink REST API exposes the state of the subtasks, and can be used in your automation. In Managed Service for Apache Flink, this requires three steps:
Make a GET request to the /jobs endpoint of the Flink REST API to retrieve the job ID.
Make a GET request to the /jobs/<job-id> endpoint to retrieve the status of the subtasks.
The following GitHub repository provides a shell script to retrieve the status of the tasks of a given Managed Service for Apache Flink application.
Monitoring subtasks failure while the job is running
The approach of polling the Flink REST API can be used in your automation, immediately after an operation, to observe whether the operation was eventually successful.
We strongly recommend not to continuously poll the Flink REST API while the job is running to detect failures. This operation is resource consuming, and might degrade performance or cause errors.
To monitor for suspicious subtask status changes during normal operations, we recommend using CloudWatch Logs instead. The following CloudWatch Logs Insights query extracts all subtask state transitions:
fields , message
| parse message /^(?<task>.+) switched from (?<fromStatus>[A-Z]+) to (?<toStatus>[A-Z]+)\./
| filter ispresent(task) and ispresent(fromStatus) and ispresent(toStatus)
| display , task, fromStatus, toStatus
| limit 10000
How Managed Service for Apache Flink minimizes processing downtime
We have seen how Flink is designed for strong consistency. To guarantee exactly-once state consistency, Flink temporarily stops the processing to deploy any changes, including scaling. This downtime is required for Flink to take a consistent copy of the application state and save it in a savepoint. After the change is deployed, the job is restarted from the savepoint, and there is no data loss. In Managed Service for Apache Flink, updates are fully managed. When snapshots are enabled, UpdateApplication automatically stops the job and uses snapshots (based on Flink’s savepoints) to retain the state.
Flink guarantees no data loss. However, your business requirements or Service Level Objectives (SLOs) might also impose a maximum delay for the data received by downstream systems, or end-to-end latency. This delay is affected by the processing downtime, or the time the job doesn’t process data to allow Flink deploying the change.With Flink, some processing downtime is unavoidable. However, Managed Service for Apache Flink is designed to minimize the processing downtime when you deploy a change.
We have seen how the service runs your application in a dedicated cluster, for complete isolation. When you issue UpdateApplication on a RUNNING application, the service prepares a new cluster with the required amount of resources. This operation might take some time. However, this doesn’t affect the processing downtime, because the service keeps the job running and processing data on the original cluster until the last possible moment, when the new cluster is ready. At this point, the service stops your job with a savepoint and restarts it on the new cluster.
During this operation, you are only charged for the number of KPU of a single cluster.
The following diagram illustrates the difference between the duration of the update operation, or the time the application status is UPDATING, and the processing downtime, observable from the job status, visible in the Flink Dashboard.
You can observe this process, keeping both the application console and Flink Dashboard open, when you update the configuration of a running application, even with no changes. The Flink Dashboard will become temporarily unavailable when the service switches to the new cluster. Additionally, you can’t use the script we provided to check the job status for this scope. Even though the cluster keeps serving the Flink Dashboard until it’s tore down, the CreateApplicationPresignedUrl action doesn’t work while the application is UPDATING.
The processing time (the time the job is not running on either clusters) depends on the time the job takes to stop with a savepoint (snapshot) and restore the state in the new cluster. This time largely depends on the size of the application state. Data skew might also affect the savepoint time due to the barrier alignment mechanism. For a deep dive into the Flink’s barrier alignment mechanism, refer to Optimize checkpointing in your Amazon Managed Service for Apache Flink applications with buffer debloating and unaligned checkpoints, keeping in mind that savepoints are always aligned.
For the scope of your automation, you normally want to wait until the job is back up and running and processing data. You normally want to set a timeout. If both the application and job don’t return to RUNNING within this timeout, something probably went wrong and you might want to raise an alarm or force a rollback. This timeout should consider the entire update operation duration.
Conclusion
In this post, we discussed possible failure scenarios when you deploy a change or scale your application. We showed how Managed Service for Apache Flink rollback functionalities can seamlessly bring you back to a safe place after a change went wrong. We also explored how you can automate monitoring operations to observe application, job, and subtask status, and how to use the fullRestarts metric to detect when the job is in a fail-and-restart loop.
Apache Flink is an open source framework for stream and batch processing applications. It excels in handling real-time analytics, event-driven applications, and complex data processing with low latency and high throughput. Flink is designed for stateful computation with exactly-once consistency guarantees for the application state.
Amazon Managed Service for Apache Flink is a fully managed stream processing service that you can use to run Apache Flink jobs at scale without worrying about managing clusters and provisioning resources. You can focus on implementing your application using your integrated development environment (IDE) of choice, and build and package the application using standard build and continuous integration and delivery (CI/CD) tools.
With Managed Service for Apache Flink, you can control the application lifecycle through simple AWS API actions. You can use the API to start and stop the application, and to apply any changes to the code, runtime configuration, and scale. The service takes care of managing the underlying Flink cluster, giving you a serverless experience. You can implement automation such as CI/CD pipelines with tools that can interact with the AWS API or AWS Command Line Interface (AWS CLI).
You can control the application using the AWS Management Console, AWS CLI, AWS SDK, and tools using the AWS API, such as AWS CloudFormation or Terraform. The service is not prescriptive on the automation tool you use to deploy and orchestrate the application.
Paraphrasing Jackie Stewart, the famous racing driver, you don’t need to understand how to operate a Flink cluster to use Managed Service for Apache Flink, but some Mechanical Sympathy will help you implement a robust and reliable automation.
In this two-part series, we explore what happens during an application’s lifecycle. This post covers core concepts and the application workflow during normal operations. In Part 2, we look at potential failures, how to detect them through monitoring, and ways to quickly resolve issues when they occur.
Definitions
Before examining the application lifecycle steps, we need to clarify the usage of certain terms in the context of Managed Service for Apache Flink:
Application – The main resource you create, control, and run in Managed Service for Apache Flink is an application.
Application code package – For each Managed Service for Apache Flink application, you implement the application code package (application artifact) of the Flink application code you want to run. This code is compiled and packaged along with dependencies into a JAR or a ZIP file, that you upload to an Amazon Simple Storage Service (Amazon S3) bucket.
Configuration – Each application has a configuration that contains the information to run it. The configuration points to the application code package in the S3 bucket and defines the parallelism, which will also determine the application resources, in terms of KPUs. It also defines security, networking, and runtime properties, which are passed to your application code at runtime.
Job – When you start the application, Managed Service for Apache Flink creates a dedicated cluster for you and runs your application code as a Flink job.
The following diagram shows the relationship between these concepts.
There are two additional important concepts: checkpoints and savepoints, the mechanisms Flink uses to guarantee state consistency across failures and operations. In Managed Service for Apache Flink, both checkpoints and savepoints are fully managed.
Checkpoints – These are controlled by the application configuration and enabled by default with a period of 1 minute. In Managed Service for Apache Flink, checkpoints are used when a job automatically restarts after a runtime failure. They are not durable and are deleted when the application is stopped or updated and when the application automatically scales.
Savepoints – These are called snapshots in Managed Service for Apache Flink, and are used to persist the application state when the application is deliberately restarted by the user, due to an update or an automatic scaling event. Snapshots can be triggered by the user. Snapshots (if enabled) are also automatically used to save and restore the application state when the application is stopped and restarted, for example to deploy a change or automatically scale. Automatic use of snapshots is enabled in the application configuration (enabled by default when you create an application using the console).
Lifecycle of an application in Managed Service for Apache Flink
Starting with the happy path, a typical lifecycle of a Managed Service for Apache Flink application comprises the following steps:
Create and configure a new application.
Start the application.
Deploy a change (update the runtime configuration, update the application code, change the parallelism to scale up or down).
Stop the application.
Starting, stopping, and updating the application use snapshots (if enabled) to retain application state consistency during operations. We recommend enabling snapshots on every production and staging application, to support the persistence of the application state across operations.
In Managed Service for Apache Flink, the application lifecycle is controlled through the console, API actions in the kinesisanalyticsv2 API, or equivalent actions in the AWS CLI and SDK. On top of these fundamental operations, you can build your own automation using different tools, directly using low-level actions or using higher level infrastructure-as-code (IaC) tooling such as AWS CloudFormation or Terraform.
In this post, we refer to the low-level API actions used at each step. Any higher-level IaC tooling will use combination of these operations. Understanding these operations is fundamental to designing a robust automation.
The following diagram summarizes the application lifecycle, showing typical operations and application statuses.
In the following sections, we analyze each lifecycle operation in more detail.
Create and configure the application
The first step is creating a new Managed Service for Apache Flink application, including defining the application configuration. You can do this in a single step using the CreateApplication action, or by creating the basic application configuration and then updating the configuration before starting it using UpdateApplication. The latter approach is what you do when you create an application from the console.
In this phase, the developer packages the application they have implemented in a JAR file (for Java) or ZIP file (for Python) and uploads it to an S3 bucket the user has previously created. The bucket name and the path to the application code package are part of the configuration you define.
When UpdateApplication or CreateApplication is invoked, Managed Service for Apache Flink takes a copy of the application code package (JAR or ZIP file) referred by the configuration. The configuration is rejected if the file pointed by the configuration doesn’t exist.
The following diagram illustrates this workflow.
Simply updating the application code package in the S3 bucket doesn’t trigger an update. You need to run UpdateApplication to make the new file visible to the service and trigger the update, even when you overwrite the code package with the same name.
Managed Service for Apache Flink indexes on high availability and runs your application in a dedicated Flink cluster. When you start the application, Managed Service for Apache Flink deploys a dedicated cluster and deploys and runs the Flink job based on the configuration you defined.
When you start the application, the status of the application moves from READY, to STARTING, and then RUNNING.
The following diagram illustrates this workflow.
Managed Service for Apache Flink supports both streaming mode, the default for Apache Flink, and batch mode:
Streaming mode – In streaming mode, after an application is successfully started and goes into RUNNING status, it keeps running until you stop it explicitly. From this point on, the behavior on failure is automatically restarting the job from the latest checkpoint, so there is no data loss. We discuss more details about this failure scenario later in this post.
Batch mode – A Flink application running in batch mode behaves differently. After you start it, it goes into RUNNING status, and the job continues running until it completes the processing. At that point the job will gracefully stop, and the Managed Service for Apache Flink application goes back to READY status.
This post focuses on streaming applications only.
Update the application
In Managed Service for Apache Flink, you handle the following changes by updating the application configuration, using the console or the UpdateApplication API action:
Application code changes, replacing the package (JAR or ZIP file) with one containing a new version
Runtime properties changes
Scaling, which implies changing parallelism and resources (KPU) changes
Operational parameter changes, such as checkpoint, logging level, and monitoring setup
Networking configuration changes
When you modify the application configuration, Managed Service for Apache Flink creates a new configuration version, identified by a version ID number, automatically incremented at every change.
Update the code package
We mentioned how the service takes a copy of the code package (JAR or ZIP file) when you update the application configuration. The copy is associated with the new application configuration version that has been created. The service uses its own copy of the code package to start the application. You can safely replace or delete the code package after you have updated the configuration. The new package is not taken into account until you update the application configuration again.
Update a READY (not running) application
If you update an application in READY status, nothing special happens beyond creating the new configuration version that will be used the next time you start the application. However, in production, you will normally update the configuration of an application in RUNNING status to apply a change. Managed Service for Apache Flink automatically handles the operations required to update the application with no data loss.
Update a RUNNING application
To understand what happens when you update a running application, you need to remember that Flink is designed for strong consistency and exactly-once state consistency. To maintain these features when a change is applied, Flink must stop the data processing, take a copy of the application state, restart the job with the changes, and restore the state, before processing can restart.
This is a standard Flink behavior, and applies to any changes, whether it’s code changes, runtime configuration changes, or new parallelism to scale up and down. Managed Service for Apache Flink automatically orchestrates this process for you. If snapshots are enabled, the service will take a snapshot before stopping the processing and restart from the snapshot when the change is deployed. This way, the change can be deployed with zero data loss.
If snapshots are disabled, the service restarts the job with the change, but the state will be empty, like the first time you started the application. This might cause data loss. You normally don’t want this to happen, particularly in production applications.
Let’s explore a practical example, illustrated by the following diagram. For instance, when you want to deploy a code change, the following steps typically happen (in this example, we assume that snapshots are enabled, which they should be in a production application):
Make changes to the application code.
The build process creates the application package (JAR or ZIP file), either manually or using CI/CD automation.
Upload the new application package to an S3 bucket.
Update the application configuration pointing to the new application package.
As soon as you successfully update the configuration, Managed Service for Apache Flink starts the operation for updating the application. The application status changes to UPDATING. The Flink job is stopped, taking a snapshot of the application state.
After the changes have been applied, the application is restarted using the new configuration, which in this case includes the new application code, and the job restores the state from the snapshot. When the process is complete, the application status goes back to RUNNING.
The process is similar for changes to the application configuration. For example, you can change the parallelism to scale the application updating the application configuration, causing the application to be redeployed with the new parallelism and the amount resources (CPU, memory, local storage) based on the new number of KPU.
Update the application’s IAM role
The application configuration contains a reference to an AWS Identity and Access Management (IAM) role. In the unlikely case you want to use a different role, you can update the application configuration using UpdateApplication. The process will be the same described earlier.
However, you usually want to modify the IAM role, to add or remove permissions. This operation doesn’t use the Managed Service for Apache Flink application lifecycle and can be done at any time. No application stop and restart is required. IAM changes take effect immediately, potentially inducing a failure if, for example, you inadvertently remove a required permission. In this case, the behavior of the Flink job’s response might vary, depending on the affected component.
Stop the application
You can stop a running Managed Service for Apache Flink application using the StopApplication action or the console. The service gracefully stops the application. The state turns from RUNNING, into STOPPING, and finally into READY.
When snapshots are enabled, the service will take a snapshot of the application state when it is stopped, as shown in the following diagram.
After you stop the application, any resource previously provisioned to run your application is reclaimed. You incur no cost while the application is not running (READY).
Start the application from a snapshot
Sometimes, you might want to stop a production application and restart it later, restarting the processing from the point it was stopped. Managed Service for Apache Flink supports starting the application from a snapshot. The snapshot saves not only the application state, but also the point in the source—the offsets in a Kafka topic, for example—where the application stopped consuming.
When snapshots are enabled, Managed Service for Apache Flink automatically takes a snapshot when you stop the application. This snapshot can be used when you restart the application.
RESTORE_FROM_LATEST_SNAPSHOT: Restore from the latest snapshot.
RESTORE_FROM_CUSTOM_SNAPSHOT: Restore from a custom snapshot (you need to specify which one).
SKIP_RESTORE_FROM_SNAPSHOT: Skip restoring from the snapshot. The application will start with no state, as the very first time you ran it.
When you start the application for the very first time, no snapshot is available yet. Regardless of the restore option you choose, the application will start with no snapshot.
The process of starting the application from a snapshot is visualized in the following diagram.
In production, you normally want to restore from the latest snapshot (RESTORE_FROM_LATEST_SNAPSHOT). This will automatically use the snapshot the service created when you last stopped the application.
Snapshots are based on Flink’s savepoint mechanism and maintain the exactly-once consistency of the internal state. Also, the risk of reprocessing duplicate records from the source is minimized because the snapshot is taken synchronously while the Flink job is stopped.
Start the application from an older snapshot
In Managed Service for Apache Flink, you can schedule taking periodic snapshots of a running production application, for example using the Snapshot Manager. Taking a snapshot from a running application doesn’t stop the processing and only introduces a minimal overhead (comparable to checkpointing). With the second option, RESTORE_FROM_CUSTOM_SNAPSHOT, you can restart the application back in time, using a snapshot older than the one taken on the last StopApplication.
Because the source positions—for example, the offsets in a Kafka topic—are also restored with the snapshot, the application will revert to the point the application was processing when the snapshot was taken. This will also restore the state at that exact point, providing consistency.
When you start an application from an older snapshot, there are two important considerations:
Only restore snapshots taken within the source system retention period – If you restore a snapshot older than the source retention, data loss might occur, and the application behavior is unpredictable.
Restarting from an older snapshot will likely generate duplicate output – This is often not a problem when the end-to-end system is designed to be idempotent. However, this might cause problems if you are using a Flink transactional connector, such as File System sink or Kafka sink with exactly-once guarantees enabled. Because these sinks are designed to guarantee no duplicates (preventing them at any cost), they might prevent your application from restarting from an older snapshot. There are workarounds to this operational problem, but they depend on the specific use case and are beyond the scope of this post.
Understanding what happens when you start your application
We have learned the fundamental operations in the lifecycle of an application. In Managed Service for Apache Flink, these operations are controlled by a few API actions, such as StartApplication, UpdateApplication, and StopApplication. The service controls every operation for you. You don’t have to provision or manage Flink clusters. However, a better understanding of what happens during the lifecycle will give you sufficient Mechanical Sympathy to recognize potential failure modes and implement a more robust automation.
Let’s see in detail what happens when you issue a StartApplication command on an application in READY (not running). When you issue an UpdateApplication command on a RUNNING application, the application is first stopped with a snapshot, and then restarted with the new configuration, with a process identical to what we are going to see.
Composition of a Flink cluster
To understand what happens when you start the application, we need to introduce a couple of additional concepts. A Flink cluster is comprised of two types of nodes:
A single Job Manager, which acts as a coordinator
One or more Task Managers, which do the actual data processing
In Managed Service for Apache Flink, you can see the cluster nodes in the Flink Dashboard, which you can access from the console.
Flink decomposes the data processing defined by your application code into one or more subtasks, which are distributed across the Task Manager nodes, as illustrated in the following diagram.
Remember, in Managed Service for Apache Flink, you don’t need to worry about provisioning and configuring the cluster. The service provides a dedicated cluster for your application. The total amount of vCPU, memory, and local storage of Task Managers matches the number of KPU you configured.
Starting your Managed Service for Apache Flink application
Now that we’ve discussed how a Flink cluster is composed, let’s explore what happens when you issue a StartApplication command, or when the application restarts after a change has been deployed with an UpdateApplication command.
The following diagram illustrates the process. Everything is carried out automatically for you.
The workflow consists of the following steps:
A dedicated cluster, with the amount of resources you requested, based on the number of KPU, is provisioned for your application.
The application code, runtime properties, and other configurations such as the application parallelism are passed to the Job Manager node, the coordinator of the cluster.
The Java or Python code in the main() method of your application is executed. This generates the logical graph of operators of your application (called dataflow). Based on the dataflow you defined and the application parallelism, Flink generates the subtasks, the actual nodes Flink will execute to process your data.
Flink then distributes the job’s subtasks across Task Managers, the actual worker nodes of the cluster.
When the previous step succeeds, the Flink job status and the Managed Service for Apache Flink application status change to RUNNING. However, the job is still not completely running and processing data. All substasks must be initialized.
Each subtask independently restores its state, if starting from a snapshot, and initializes runtime resources. For example, Flink’s Kafka source connector restores the partition assignments and offsets from the savepoint (snapshot), establishes a connection to the Kafka cluster, and subscribes to the Kafka topic. From this step onward, a Flink job will stop and restart from its last checkpoint when encountering any unhandled error. If the problem causing the error is not transient, the job keeps stopping and restarting from the same checkpoint in a loop.
When all subtasks are successfully initialized and change to RUNNING status, the Flink job starts processing data and is now properly running.
Conclusion
In this post, we discussed how the lifecycle of a Managed Service for Apache Flink application is controlled by simple AWS API commands, or the equivalent using the AWS SDK or AWS CLI. If you are using high-level automation tools such as AWS CloudFormation or Terraform, the low-level actions are also abstracted away for you. The service handles the complexity of operating the Flink cluster and orchestrating the Flink job lifecycle.
However, with a better understanding of how Flink works and what the service does for you, you can implement more robust automation and troubleshoot failures.
In the Part 2, we continue examining failure scenarios that can happen during normal operations or when you deploy a change or scale the application, and how to monitor operations to detect and recover when something goes wrong.
This post demonstrates how to build a secure search application using Amazon OpenSearch Service and JSON Web Tokens (JWTs). We discuss the basics of OpenSearch Service and JWTs and how to implement user authentication and authorization through an existing identity provider (IdP). The focus is on enforcing fine-grained access control based on user roles and permissions.
JWT authentication and authorization for your OpenSearch Service domain provides a robust mechanism that addresses requirements for fine-grained access control. An IdP is a service that stores and manages user identities and their access rights, enabling centralized user authentication across multiple applications. The IdP issues JWTs, which are secure tokens containing claims about the authenticated user. By using JWTs from the IdP, you can:
Implement secure, role-based access control to search results
Validate user permissions before granting access to sensitive data
Maintain a centralized authentication mechanism across your search application
Make sure only authorized users can view data based on their predefined roles
The JWT integration helps organizations:
Define granular permissions within the IdP
Authenticate users using bearer tokens across different applications
Protect sensitive information through token-based access management
Reduce complexity of managing multiple authentication systems
Key benefits of the solution include:
Standardized token-based authentication
Centralized permission management
Simplified single sign-on (SSO) experience
Flexible and scalable access control mechanism
The ability to dynamically filter sensitive information based on token claims enhances data security while reducing the complexity of managing multiple authentication systems. This capability is made possible through the fine-grained access control (FGAC) feature in OpenSearch Service, which enforces document- and field-level access based on user roles.
Use case overview
In this post, we explore a user workflow with multiple roles and access level requirements. A research institution wants to build a secure search application with controlled access to biomedical databases specifically PubMed (a comprehensive database of biomedical literature) and Clinical Trials (a registry of medical research studies). Different research teams require varying levels of access to these datasets based on their roles and clearance levels. The following hierarchical access structure defines the user roles and their corresponding permission levels for accessing PubMed and Clinical Trials databases:
PubMed Admin – Full read access to all PubMed data (for senior research groups)
PubMed Limited – Restricted access to specific fields and documents (for researchers with limited access)
Clinical Trials Admin – Full read access to all Clinical Trials data (for principal investigators and senior trial managers)
Clinical Trials Limited – Restricted read access to specific trial information and aggregated data (for trial researchers with limited access)
Research Basic – Read-only access to specific public data in PubMed and Clinical Trials (for general research staff and interns)
Research Full Access – Full read and write access to all indices, with permissions to update or modify data
To implement this use case, we use JWTs generated by the supported IdP, which encode role-specific information. This setup makes sure OpenSearch Service can validate tokens before returning search results, dynamically filtering sensitive data based on the user’s JWT claims and fine-grained access control settings.
Solution overview
The technical workflow for using JWT authorization with OpenSearch Service involves several key stages:
User authentication – Users log in through the existing authentication system linked to the IdP
JWT generation – Upon successful authentication, the IdP generates a JWT containing specific role information
Search query submission – Users submit search queries to OpenSearch Service along with their JWT
Token validation – OpenSearch Service validates and decodes the JWT to verify user permissions
Result filtering – Search results are filtered based on the user’s permissions defined in the JWT
Data retrieval – Only authorized data is returned to the user, enforcing compliance with privacy standards
This workflow provides a standardized approach to authentication and authorization while streamlining user interactions with the search application. The solution makes sure each user sees only the information appropriate to their role, maintaining data privacy and organizational security standards.
The following diagram illustrates the solution architecture.
This solution demonstrates authentication using Amazon Cognito as the IdP to generate the JWT. However, you can use another supported IdP. The ID token includes group membership information that OpenSearch Service maps to roles configured using fine-grained access control.
The user flow consists of the following steps:
The client initiates authentication by logging in with Amazon Cognito user credentials. Amazon Cognito returns an authorization code.
The client sends the authorization code to an Amazon API Gateway /token endpoint for ID token exchange.
API Gateway forwards the authorization code to an AWS Lambda function.
The Lambda function sends a token exchange request to Amazon Cognito with the authorization code.
The Lambda function receives the ID token from Amazon Cognito and returns it to the client.
The client sends an OpenSearch Service query to the API Gateway /search endpoint, including the ID token. API Gateway validates the ID token (JWT) with Amazon Cognito.
API Gateway forwards the request to a Lambda function.
The Lambda function checks if JWT authentication and authorization is enabled for the OpenSearch Service domain with the respective public key of the Amazon Cognito user pool. If not, it will enable and configure this feature for the OpenSearch Service domain. The Lambda function forwards the query and ID token to OpenSearch Service.
OpenSearch Service validates the JWT with Amazon Cognito:
OpenSearch Service verifies user permissions against fine-grained access control based on group membership.
OpenSearch Service returns query results to the client if authorization succeeds.
The following diagram illustrates the request flow.
Prerequisites
Before you deploy the solution, make sure you have the following prerequisites:
To deploy the solution resources, we use an AWS CloudFormation template. Launch the AWS CloudFormation template with the following Launch Stack button.
Enter an appropriate stack name. This name is used as a prefix for resources like OpenSearch Service domains and Lambda functions. Keep the default settings, and choose Create.
The stack deployment takes approximately 15–20 minutes. When deployment is complete, the stack status shows as CREATE_COMPLETE.
The outputs for this CloudFormation stack show important information regarding the deployed resources. This information will be referenced throughout different sections of this post.
On the Outputs tab, note the following values:
OpenSearchDashboardURL
SharedLambdaRoleArn
On the Resources tab, locate the following information:
OpenSearchMasterUserSecret: Choose the Physical ID link, then choose Retrieve Secret Value. Note the user name and password required for OpenSearch Service domain login.
IngestDataAndCreateBackendRoles: Choose the Physical ID link to open the Lambda function, needed in later steps.
UserPool: Choose the Physical ID link to open the Amazon Cognito user pool, needed in later steps.
RestAPI: Choose the Physical ID link to open the API Gateway endpoint, needed in later sections.
In a separate browser tab, log in to the OpenSearch dashboard using OpenSearchDashboardsURL and user credentials noted previously.
Assign permissions to the IAM role associated with the Lambda function
Complete the following steps to map your IAM role to both the all_access and security_manager roles in OpenSearch Service:
In OpenSearch Dashboards, choose Security in the navigation pane, then choose Roles.
Open the all_access role.
In the Mapped users section, choose Manage mapping.
For Backend role, enter the IAM role Amazon Resource name (ARN). This is the value you copied from the CloudFormation stack output for SharedLambdaRoleArn.
Choose Map to confirm.
On the Roles page, open the security_manager role.
In the Mapped users section, choose Manage mapping.
For Backend role, enter the same IAM role ARN.
Choose Map to confirm the changes.
These steps ensure the IAM role attached to the Lambda function has the necessary permissions to ingest data (all_access) and create roles (security_manager) within the OpenSearch Service domain.
In this sample setup, the Lambda function handles bulk ingestion and role creation without granting any direct access to users, and all_access is provided to the Lambda role solely to enable ingestion. FGAC in OpenSearch provides in-depth access control, allowing you to further tighten the Lambda role permissions by granting only the necessary CRUD operations, rather than full access for ingestion. For more details, refer to Defining users and roles and Fine-grained access control in OpenSearch.
Run the Lambda function to ingest data into the OpenSearch Service domain
On the CloudFormation stack’s Resources tab, locate the IngestDataAndCreateBackendRoles Lambda function. Open the Lambda function, choose Test, and execute it. You can confirm the function’s successful execution by checking Amazon CloudWatch Logs.
This Lambda function is designed to perform bulk ingestion and role creation in the OpenSearch Service domain. It ingests sample clinical research data into OpenSearch Service, creating two indexes (pubmed and clinical_trials), and sets up required OpenSearch Service roles. We explore these roles in detail in the next section.
Map roles and users in OpenSearch Service
In this step, we define two key OpenSearch Service roles:
pubmed-admin – Grants full read access to the PubMed index containing biomedical literature and research abstracts, intended for senior research groups
pubmed-limited – Provides restricted read access to only specific fields (journal, title, and abstract, where journal is a masked field), intended for researchers with limited data access
We have already created these roles by running the Lambda function in the previous section. The following code is the pubmed-admin OpenSearch Service role description:
The following code is the pubmed-limited OpenSearch Service role description:
The pubmed-admin and pubmed-limited roles serve different purposes, and their main distinction lies in how they control data visibility. Document-level security (DLS) lets you restrict a role to a subset of documents in an index, while field-level security (FLS) lets you control which document fields a user can see. The limited role is configured with FLS to expose only the journal, title, and abstract fields, while masked fields anonymize sensitive data such as journal. On top of these, you can apply DLS to hide specific records, for example, to prevent users from viewing documents from certain journals or publication years. In your use cases, use DLS and FLS to control document and field visibility for different users. These roles are fully configurable; you can add, remove, or update document and field access at any time to match evolving security or business requirements.
To enforce access control, users need to be mapped to appropriate OpenSearch Service roles on OpenSearch Dashboards. Complete the following steps to map users to the OpenSearch Service roles:
On OpenSearch Dashboards, choose Security in the navigation pane, then choose Roles.
Open the pubmed-admin role.
In the Mapped users section, choose Manage mapping.
For Backend role, enter pubmed_admin_group.
Choose Map to confirm the mapping.
On the Roles page, open the pubmed-limited role.
In the Mapped users section, choose Manage mapping.
For Backend role, enter pubmed_limited_group.
Choose Map to confirm the mapping.
Backend roles simplify access management in OpenSearch Service. Instead of mapping individual users to OpenSearch service roles, you can map roles to backend roles that users share. This approach lets you map IdP groups directly to the OpenSearch service roles. OpenSearch Service provides options when configuring your OpenSearch Service domain to map JWT claims to OpenSearch Service roles using the roles key.
In this solution, the JWT contains a field called cognito:groups that will be mapped as the roles key. In every JWT, this field has a value for the appropriate group the user belongs to. Based on the field value in the JWT and the mapping defined in the previous step for different research groups, OpenSearch Service domain dynamically assigns permissions:
If the JWT contains “cognito:groups”: [“pubmed_admin_group”], the user is granted pubmed_admin access
If the JWT contains “cognito:groups”: [“pubmed_limited_group”], the user is granted pubmed_limited access
Take a look at the examples below to understand what a JWT header and payload look like.
The email address required for each user should be unique. If your email domain supports email alias, you can add a suffix to your own email address by using [email protected]. The following screenshot shows our users.
On the CloudFormation stack’s Resources tab, locate the UserPool Amazon Cognito user pool that you noted earlier. Open the user pool in a new browser tab.
To create the Amazon Cognito users, complete the following steps for each user:
On the Amazon Cognito console, choose Users in the navigation pane.
Choose Create user.
For Alias attributes used to sign in, select Email.
For User name, enter a unique user name.
For Email address, enter a unique email address for each user.
To create the Amazon Cognito groups, complete the following steps for each group:
On the Amazon Cognito console, choose Groups in the navigation pane.
Choose Create group.
For Group name, enter a unique name.
Choose Create group.
Add Amazon Cognito users to groups
The users should be added to the groups as follows:
Add PubMedAdminUser to the pubmed_admin_group group
Add PubMedLimitedUser to the pubmed_limited_group group
Add ClinicalTrialsAdminUser to the clinical_trials_admin_group group
Add ClinicalTrialsLimitedUser to the clinical_trials_limited_group group
Add ResearchBasicUser to the research_basic_group group
To add users to their respective group, complete the following steps for each group:
On the Amazon Cognito console, choose Groups in the navigation pane.
Choose the group to which you want to add a user.
Choose Add user to group.
Choose the user and choose Add.
Log in to generate a JWT
Before running the test queries in the next section, you must obtain the id_token (JWT) for the specified users. The tokens will expire in 60 minutes. If the token is expired for a user, you must log in again to get a fresh token. To log in with your user to get the id_token, complete the following steps:
On the Amazon Cognito console, open your user pool.
Choose App clients in the navigation pane.
Choose the app client.
Choose View login page.
Enter the user name that you used when creating the user.
Enter the temporary password that you set when creating the user.
For first-time logins, you will be prompted to create a new password. Enter a new password that meets the following requirements:
At least 8 characters
Contains uppercase and lowercase letters
Contains at least one number
Contains at least one special character
Copy the id_token value you generated (without quotation marks).
Query data in OpenSearch Service
This example demonstrates how OpenSearch Service filters search results based on user permissions. We test searches using JWTs for two different users to verify access controls. Each user’s search results are limited to the indexes and documents allowed by their assigned roles.
On the CloudFormation stack’s Resources tab, locate the RestAPI value that you noted earlier. Open the API gateway in a new browser tab.
Complete the following steps to test the search API for each of the scenarios mentioned in this section:
On the API Gateway console, choose Resources in the navigation pane.
Choose the /search resource.
Choose the POST method.
Choose Test.
When submitting queries to OpenSearch Service, make sure all double quotation marks are escaped to prevent syntax errors. Additionally, make sure you complete your query before your JWT expires, or you will need to generate a new token. If you attempt to use an expired token, it will result in an error.
For Scenarios 1 and 2, log in with your PubMedAdmin user, and for Scenarios 3 and 4, log in with your PubMedLimitedUser to obtain the required id_token.
Scenario 1
In this first query, we query the pubmed index with the credentials of user PubMedAdminUser, which is part of pubmed_admin_group:
{
  "query": {
    "match_all": {}
  }
}
Add the following values to the respective input fields:
For Query strings, enter query="{\"query\":{\"match_all\":{}}}"&index=pubmed
For Headers, enter id_token:<id-token-for-PubMedAdminUser>
The following screenshot shows our query results.
Users with the pubmed_admin role have full access to the PubMed index and can perform unrestricted searches across all fields and document types. This query successfully returns documents with the HTTP 200 status code because the user has complete read permissions on this index.
Scenario 2
Next, we query the clinical-trials index with the credentials of user PubMedAdminUser, who is part of pubmed_admin_group:
{
  "query": {
    "match_all": {}
  }
}
Add the following values to the respective input fields:
For Query strings, enter query="{\"query\":{\"match_all\":{}}}"&index=clinical-trials
For Headers, enter id_token:<id-token-for-PubMedAdminUser>
The following screenshot shows our query results.
Despite having admin privileges for PubMed data, this user receives a 403 Forbidden response when attempting to access the clinical-trials index. The error message indicates the lack of necessary permissions for performing search operations on this index.
Scenario 3
Now we query allowed fields in the pubmed index with the credentials of user PubMedLimitedUser, which is part of pubmed_limited_group:
Add the following values to the respective input fields:
For Query strings, enter query="{\"query\":{\"match\":{\"title\": \"molecular biology\"}}}"&index=pubmed
For Headers, enter id_token:<id-token-for-PubMedLimitedUser>
The following screenshot shows our query results.
Users with the pubmed_limited role can successfully query specific fields like title, but with restricted access to sensitive information. The query returns results with the HTTP 200 status code, but the journal field is anonymized due to field-level security policies. Users can search and view certain fields while having sensitive data automatically masked or excluded from their results.
Scenario 4
Lastly, we query unauthorized fields in the pubmed index with the credentials of user PubMedLimitedUser, which is part of pubmed_limited_group:
Add the following values to the respective input fields:
For Query strings, enter query="{\"query\":{\"match\":{\"research_group\":\"RG_345\"}}}"&index=pubmed
For Headers, enter id_token:<id-token-for-PubMedLimitedUser>
The following screenshot shows our query results.
When a user with the pubmed_limited role attempts to query the restricted research_group field, OpenSearch returns a successful response (HTTP 200) but with empty results. This behavior occurs because field-level security is enforcing access controls instead of returning a HTTP 403 error, it silently filters out the restricted field from both the query and results. This security-by-obscurity approach means that users can’t determine whether their query failed due to lack of permissions or genuine absence of matching documents.
Clean up
To avoid incurring further AWS usage charges, delete the resources created in this post by deleting the CloudFormation stack. This step will remove all resources except Lambda layers. To delete the Lambda layers, navigate to the Layers page on the Lambda console, and delete the layers named <CloudFormation-Stack-Name>-requests and <CloudFormation-Stack-Name>-crypt.
Conclusion
In this post, we discussed how JWTs provide a robust and scalable authentication mechanism that can be integrated with existing IdPs. We also demonstrated how to seamlessly integrate fine-grained access control across search applications. Organizations can define granular permissions within their IdP, making sure sensitive information remains protected. The JWT integration with OpenSearch Service enables secure, efficient access control, so users can only access role-appropriate information while simplifying compliance and access management.
Ramya Bhat is a Data Analytics Consultant at AWS, specializing in the design and implementation of cloud-based data platforms. She builds enterprise-grade solutions across search, data warehousing, and ETL that enable organizations to modernize data ecosystems and derive insights through scalable analytics. She has delivered customer engagements across healthcare, insurance, fintech, and media sectors.
Shubhansu Sawaria is a Sr. Delivery Consultant – SRC at AWS, based in Bangalore, India. He specializes in designing and implementing comprehensive AWS Cloud security solutions. He has developed security solutions for startups, banks, and healthcare organizations. His expertise helps organizations elevate their cloud security infrastructures, achieve compliance objectives, and provide robust data protection.
Soujanya Konka is a Sr. Solutions Architect and Analytics Specialist at AWS, focused on helping customers build their ideas in the cloud. She has expertise in designing and implementing enterprise search solutions and advanced data analytics at scale.
Organizations face significant challenges when deploying large language models (LLMs) efficiently at scale. Key challenges include optimizing GPU resource utilization, managing network infrastructure, and providing efficient access to model weights.When running distributed inference workloads, organizations often encounter complexity in orchestrating model operations across multiple nodes. Common challenges include effectively distributing model components across available GPUs, coordinating seamless communication between processing units, and maintaining consistent performance with low latency and high throughput.
vLLM is an open source library for fast LLM inference and serving. The vLLM AWS Deep Learning Containers (DLCs) are optimized for customers deploying vLLMs on Amazon Elastic Compute Cloud (Amazon EC2), Amazon Elastic Container Service (Amazon ECS), and Amazon Elastic Kubernetes Service (Amazon EKS), and are provided at no additional charge. These containers package a preconfigured, pre-tested environment that functions seamlessly out of the box, includes the necessary dependencies such as drivers and libraries for running vLLMs efficiently, and offers built-in support for Elastic Fabric Adapter (EFA) for high-performance multi-node inference workloads. You don’t have to build the inference environment from scratch anymore. Instead, you can install the vLLM DLC and it will automatically set up and configure the environment, and you can start deploying the inference workloads at scale.
In this post, we demonstrate how to deploy the DeepSeek-R1-Distill-Qwen-32B model using AWS DLCs for vLLMs on Amazon EKS, showcasing how these purpose-built containers simplify deployment of this powerful open source inference engine. This solution can help you solve the complex infrastructure challenges of deploying LLMs while maintaining performance and cost-efficiency.
AWS DLCs
AWS DLCs provide generative AI practitioners with optimized Docker environments to train and deploy generative AI models in their pipelines and workflows across Amazon EC2, Amazon EKS, and Amazon ECS. AWS DLCs are targeted for self-managed machine learning (ML) customers who prefer to build and maintain their AI/ML environments on their own, want instance-level control over their infrastructure, and manage their own training and inference workloads. DLCs are available as Docker images for training and inference, and also with PyTorch and TensorFlow.DLCs are kept current with the latest version of frameworks and drivers, are tested for compatibility and security, and are offered at no additional cost. They are also quickly customizable by following our recipe guides. Using AWS DLCs as a building block for generative AI environments reduces the burden on operations and infrastructure teams, lowers TCO for AI/ML infrastructure, accelerates the development of generative AI products, and helps the generative AI teams focus on the value-added work of deriving generative AI-powered insights from the organization’s data.
Solution overview
The following diagram shows the interaction between Amazon EKS, GPU-enabled EC2 instances with EFA networking, and Amazon FSx for Lustre storage. Client requests flow through the Application Load Balancer (ALB) to the vLLM server pods running on EKS nodes, which access model weights stored on FSx for Lustre. This architecture provides a scalable, high-performance solution for serving LLM inference workloads with optimal cost-efficiency.
The following diagram illustrates the DLC stack on AWS. The stack demonstrates a comprehensive architecture from EC2 instance foundation through container runtime, essential GPU drivers, and ML frameworks like PyTorch. The layered diagram shows how CUDA, NCCL, and other critical components integrate to support high-performance deep learning workloads.
The vLLM DLCs are specifically optimized for high-performance inference, with built-in support for tensor parallelism and pipeline parallelism across multiple GPUs and nodes. This optimization enables efficient scaling of large models like DeepSeek-R1-Distill-Qwen-32B, which would otherwise be challenging to deploy and manage. The containers also include optimized CUDA configurations and EFA drivers, facilitating maximum throughput for distributed inference workloads. This solution uses the following AWS services and components:
AWS DLCs for vLLMs – Pre-configured, optimized Docker images that simplify deployment and maximize performance
EKS cluster – Provides the Kubernetes control plane for orchestrating containers
P4d.24xlarge instances – EC2 P4d instances with 8 NVIDIA A100 GPUs each, configured in a managed node group
Elastic Fabric Adapter – Network interface that enables high-performance computing applications to scale efficiently
FSx for Lustre – High-performance file system for storing model weights
LeaderWorkerSet pattern – Custom Kubernetes resource for deploying vLLM in a distributed configuration
AWS Load Balancer Controller – Manages the ALB for external access
By combining these components, we create an inference system that delivers low-latency, high-throughput LLM serving capabilities with minimal operational overhead.
Prerequisites
Before getting started, make sure you have the following prerequisites:
Create, manage, and delete EC2 resources, including virtual private clouds (VPCs), subnets, security groups, and internet gateways (see Identity-based policies for Amazon EC2 for more details)
This solution can be deployed in AWS Regions where Amazon EKS, P4d instances, and FSx for Lustre are available. This guide uses the us-west-2 Region. The complete deployment process takes approximately 60–90 minutes.
Clone our GitHub repository containing the necessary configuration files:
# Clone the repository
git clone https://github.com/aws-samples/sample-aws-deep-learning-containers.git
cd vllm-samples/deepseek/eks
Create an EKS cluster
First, we create an EKS cluster in the us-west-2 Region using the provided configuration file. This sets up the Kubernetes control plane that will orchestrate our containers. The cluster is configured with a VPC, subnets, and security groups optimized for running GPU workloads.
# Update the region in eks-cluster.yaml if needed
sed -i "s|region: us-east-1|region: us-west-2|g" eks-cluster.yaml

# Create the EKS cluster
eksctl create cluster -f eks-cluster.yaml --profile vllm-profile
This will take approximately 15–20 minutes to complete. During this time, eksctl creates a CloudFormation stack that provisions the necessary resources for your EKS cluster, as shown in the following screenshot.
You can validate the cluster creation with the following code:
# Verify cluster creation
eksctl get cluster --profile vllm-profile
Expected output:
NAME            REGION          EKSCTL CREATED
vllm-cluster    us-west-2       True
You can also see the cluster created on the Amazon EKS console.
Create a node group with EFA support
Next, we create a managed node group with P4d.24xlarge instances that have EFA enabled. These instances are equipped with 8 NVIDIA A100 GPUs each, providing substantial computational power for LLM inference. When deploying EFA-enabled instances like p4d.24xlarge for high-performance ML workloads, you must place them in private subnets to facilitate secure, optimized networking. By dynamically identifying and using a private subnet’s Availability Zone in your node group configuration, you can maintain proper network isolation while supporting the high-throughput, low-latency communication essential for distributed training and inference with LLMs. We identify the Availability Zone using the following code:
# Get the VPC ID from the EKS cluster
VPC_ID=$(aws --profile vllm-profile eks describe-cluster --name vllm-cluster \
  --query "cluster.resourcesVpcConfig.vpcId" --output text)

# Find the one of private subnet's availability zone
PRIVATE_AZ=$(aws --profile vllm-profile ec2 describe-subnets \
  --filters "Name=vpc-id,Values=$VPC_ID" "Name=map-public-ip-on-launch,Values=false" \
  --query "Subnets[0].AvailabilityZone" --output text)
echo "Selected private subnet AZ: $PRIVATE_AZ"

# update the nodegroup_az section with the private AZ value
sed -i "s|availabilityZones: \[nodegroup_az\]|availabilityZones: \[\"$PRIVATE_AZ\"\]|g" large-model-nodegroup.yaml

# Verify the change
grep "availabilityZones" large-model-nodegroup.yaml

# Create the node group with EFA support
eksctl create nodegroup -f large-model-nodegroup.yaml --profile vllm-profile
This will take approximately 10–15 minutes to complete. The EFA configuration is particularly important for multi-node deployments, because it enables high-throughput, low-latency networking between nodes. This is crucial for distributed inference workloads where communication between GPUs on different nodes can become a bottleneck. After the node group is created, configure kubectl to connect to the cluster:
# Configure kubectl to connect to the cluster
aws eks update-kubeconfig --name vllm-cluster --region us-west-2 --profile vllm-profile
Verify that the nodes are ready:
# Check node status
kubectl get nodes
The following is an example of the expected output:
NAME                                            STATUS   ROLES    AGE     VERSION
ip-192-168-xx-xx.us-west-2.compute.internal     Ready    <none>   5m      v1.31.7-eks-xxxx
ip-192-168-yy-yy.us-west-2.compute.internal     Ready    <none>   5m      v1.31.7-eks-xxxx
You can also see the node group created on the Amazon EKS console.
Check NVIDIA device pods
Because we’re using an Amazon EKS optimized AMI with GPU support (ami-0ad09867389dc17a1), the NVIDIA device plugin is already included in the cluster, so there’s no need to install it separately. Verify that the NVIDIA device plugin is running:
# Check available GPUs
kubectl get nodes -o json | jq '.items[].status.capacity."nvidia.com/gpu"'
The following is our expected output:
"8"
"8"
Create an FSx for Lustre file system
For optimal performance, we create an FSx for Lustre file system to store our model weights. FSx for Lustre provides high-throughput, low-latency access to data, which is essential for loading large model weights efficiently. We use the following code:
# Create a security group for FSx Lustre
FSX_SG_ID=$(aws --profile vllm-profile ec2 create-security-group --group-name fsx-lustre-sg \
  --description "Security group for FSx Lustre" \
  --vpc-id $(aws --profile vllm-profile eks describe-cluster --name vllm-cluster \
  --query "cluster.resourcesVpcConfig.vpcId" --output text) \
  --query "GroupId" --output text)

echo "Created security group: $FSX_SG_ID"

# Add inbound rules for FSx Lustre
aws --profile vllm-profile ec2 authorize-security-group-ingress --group-id $FSX_SG_ID \
  --protocol tcp --port 988-1023 \
  --source-group $(aws --profile vllm-profile eks describe-cluster --name vllm-cluster \
  --query "cluster.resourcesVpcConfig.clusterSecurityGroupId" --output text)

aws --profile vllm-profile ec2 authorize-security-group-ingress --group-id $FSX_SG_ID \
     --protocol tcp --port 988-1023 \
     --source-group $FSX_SG_ID

# Create the FSx Lustre filesystem
SUBNET_ID=$(aws --profile vllm-profile eks describe-cluster --name vllm-cluster \
  --query "cluster.resourcesVpcConfig.subnetIds[0]" --output text)

echo "Using subnet: $SUBNET_ID"

FSX_ID=$(aws --profile vllm-profile fsx create-file-system --file-system-type LUSTRE \
  --storage-capacity 1200 --subnet-ids $SUBNET_ID \
  --security-group-ids $FSX_SG_ID --lustre-configuration DeploymentType=SCRATCH_2 \
  --tags Key=Name,Value=vllm-model-storage \
  --query "FileSystem.FileSystemId" --output text)

echo "Created FSx filesystem: $FSX_ID"

# Wait for the filesystem to be available (typically takes 5-10 minutes)
echo "Waiting for filesystem to become available..."
aws --profile vllm-profile fsx describe-file-systems --file-system-id $FSX_ID \
  --query "FileSystems[0].Lifecycle" --output text

# You can run the above command periodically until it returns "AVAILABLE"
# Example: watch -n 30 "aws --profile vllm-profile fsx describe-file-systems --file-system-id $FSX_ID --query FileSystems[0].Lifecycle --output text"

# Get the DNS name and mount name
FSX_DNS=$(aws --profile vllm-profile fsx describe-file-systems --file-system-id $FSX_ID \
  --query "FileSystems[0].DNSName" --output text)

FSX_MOUNT=$(aws --profile vllm-profile fsx describe-file-systems --file-system-id $FSX_ID \
  --query "FileSystems[0].LustreConfiguration.MountName" --output text)

echo "FSx DNS: $FSX_DNS"
echo "FSx Mount Name: $FSX_MOUNT"
The file system is configured with 1.2 TB of storage capacity, SCRATCH_2 deployment type for high performance, and security groups that allow access from our EKS nodes. You can also check the FSx for Lustre file system on the FSx for Lustre console.
Install the AWS FSx CSI Driver
To mount the FSx for Lustre file system in our Kubernetes pods, we install the AWS FSx CSI Driver. This driver enables Kubernetes to dynamically provision and mount FSx for Lustre volumes.
We create the necessary Kubernetes resources to use our FSx for Lustre file system:
# Update the storage class with your subnet and security group IDs
sed -i "s|<subnet-id>|$SUBNET_ID|g" fsx-storage-class.yaml
sed -i "s|<sg-id>|$FSX_SG_ID|g" fsx-storage-class.yaml

# Update the PV with your FSx Lustre details
sed -i "s|<fs-id>|$FSX_ID|g" fsx-lustre-pv.yaml
sed -i "s|<fs-id>.fsx.us-west-2.amazonaws.com|$FSX_DNS|g" fsx-lustre-pv.yaml
sed -i "s|<mount-name>|$FSX_MOUNT|g" fsx-lustre-pv.yaml

# Apply the Kubernetes resources
kubectl apply -f fsx-storage-class.yaml
kubectl apply -f fsx-lustre-pv.yaml
kubectl apply -f fsx-lustre-pvc.yaml
Verify that the resources were created successfully:
# Check storage class
kubectl get sc fsx-sc

# Check persistent volume
kubectl get pv fsx-lustre-pv

# Check persistent volume claim
kubectl get pvc fsx-lustre-pvc
The following is an example of the expected output:
NAME     PROVISIONER      RECLAIMPOLICY   VOLUMEBINDINGMODE   ALLOWVOLUMEEXPANSION   AGE
fsx-sc   fsx.csi.aws.com   Retain          Immediate           false                  1m

NAME             CAPACITY   ACCESS MODES   RECLAIM POLICY   STATUS   CLAIM                  STORAGECLASS   REASON   AGE
fsx-lustre-pv   1200Gi     RWX            Retain           Bound    default/fsx-lustre-pvc  fsx-sc                  1m

NAME             STATUS   VOLUME           CAPACITY   ACCESS MODES   STORAGECLASS   AGE
fsx-lustre-pvc   Bound    fsx-lustre-pv   1200Gi     RWX            fsx-sc         1m
These resources include:
A StorageClass that defines how to provision FSx for Lustre volumes
A PersistentVolume that represents our existing FSx for Lustre file system
A PersistentVolumeClaim that our pods will use to mount the file system
Install the AWS Load Balancer Controller
To expose our vLLM service to the outside world, we install the AWS Load Balancer Controller. This controller manages ALBs for our Kubernetes services and ingresses. Refer to Install AWS Load Balancer Controller with Helm for addition details.
# Download the IAM policy document
curl -o iam-policy.json https://raw.githubusercontent.com/kubernetes-sigs/aws-load-balancer-controller/main/docs/install/iam_policy.json

# Create the IAM policy
aws --profile vllm-profile iam create-policy --policy-name AWSLoadBalancerControllerIAMPolicy --policy-document file://iam-policy.json

# Create an IAM OIDC provider for the cluster
eksctl utils associate-iam-oidc-provider --profile vllm-profile --region=us-west-2 --cluster=vllm-cluster --approve

# Create an IAM service account for the AWS Load Balancer Controller
ACCOUNT_ID=$(aws --profile vllm-profile sts get-caller-identity --query "Account" --output text)
eksctl create iamserviceaccount \
  --profile vllm-profile \
  --cluster=vllm-cluster \
  --namespace=kube-system \
  --name=aws-load-balancer-controller \
  --attach-policy-arn=arn:aws:iam::$ACCOUNT_ID:policy/AWSLoadBalancerControllerIAMPolicy \
  --override-existing-serviceaccounts \
  --approve

# Install the AWS Load Balancer Controller using Helm
helm repo add eks https://aws.github.io/eks-charts
helm repo update

# Install the CRDs
kubectl apply -f https://raw.githubusercontent.com/aws/eks-charts/master/stable/aws-load-balancer-controller/crds/crds.yaml

# Install the controller
helm install aws-load-balancer-controller eks/aws-load-balancer-controller \
  -n kube-system \
  --set clusterName=vllm-cluster \
  --set serviceAccount.create=false \
  --set serviceAccount.name=aws-load-balancer-controller
Verify that the AWS Load Balancer Controller is running:
We create a dedicated security group for the ALB and configure it to allow inbound traffic on port 80 from our client IP addresses. We also configure the node security group to allow traffic from the ALB security group to the vLLM service port.
# Create security group for the ALB
USER_IP=$(curl -s https://checkip.amazonaws.com)

VPC_ID=$(aws --profile vllm-profile eks describe-cluster --name vllm-cluster \
  --query "cluster.resourcesVpcConfig.vpcId" --output text)

ALB_SG=$(aws --profile vllm-profile ec2 create-security-group \
  --group-name vllm-alb-sg \
  --description "Security group for vLLM ALB" \
  --vpc-id $VPC_ID \
  --query "GroupId" --output text)

echo "ALB security group: $ALB_SG"

# Allow inbound traffic on port 80 from your IP
aws --profile vllm-profile ec2 authorize-security-group-ingress \
  --group-id $ALB_SG \
  --protocol tcp \
  --port 80 \
  --cidr ${USER_IP}/32

# Get the node group security group ID
NODE_INSTANCE_ID=$(aws --profile vllm-profile ec2 describe-instances \
  --filters "Name=tag:eks:nodegroup-name,Values=vllm-p4d-nodes-efa" \
  --query "Reservations[0].Instances[0].InstanceId" --output text)

NODE_SG=$(aws --profile vllm-profile ec2 describe-instances \
  --instance-ids $NODE_INSTANCE_ID \
  --query "Reservations[0].Instances[0].SecurityGroups[0].GroupId" --output text)

echo "Node security group: $NODE_SG"

# Allow traffic from ALB security group to node security group on port 8000 (vLLM service port)
aws --profile vllm-profile ec2 authorize-security-group-ingress \
  --group-id $NODE_SG \
  --protocol tcp \
  --port 8000 \
  --source-group $ALB_SG

# Update the security group in the ingress file
sed -i "s|<sg-id>|$ALB_SG|g" vllm-deepseek-32b-lws-ingress.yaml
Verify that the security groups were created and configured correctly:
# Verify ALB security group
aws --profile vllm-profile ec2 describe-security-groups --group-ids $ALB_SG --query "SecurityGroups[0].IpPermissions"
The following is the expected output for the ALB security group:
[
    {
        "FromPort": 80,
        "IpProtocol": "tcp",
        "IpRanges": [
            {
                "CidrIp": "USER_IP/32"
            }
        ],
        "ToPort": 80
    }
]
# Verify node security group rules
aws --profile vllm-profile ec2 describe-security-groups --group-ids $NODE_SG --query "SecurityGroups[0].IpPermissions"
Deploy the vLLM server
Finally, we deploy the vLLM server using the LeaderWorkerSet pattern. The AWS DLCs provide an optimized environment that minimizes the complexity typically associated with deploying LLMs.The vLLM DLCs come preconfigured with the following features:
Optimized CUDA libraries for maximum GPU utilization
EFA drivers and configurations for high-speed node-to-node communication
Ray framework setup for distributed computing
Performance-tuned vLLM installation with support for tensor and pipeline parallelism
This prepackaged solution dramatically reduces deployment time, the need for complex environment setup, dependency management, and performance tuning that would otherwise require specialized expertise.
# Deploy the vLLM server
# First, verify that the AWS Load Balancer Controller is running
kubectl get pods -n kube-system | grep aws-load-balancer-controller

# Wait until the controller is in Running state
# If it's not running, check the logs:
# kubectl logs -n kube-system deployment/aws-load-balancer-controller

# Apply the LeaderWorkerSet
kubectl apply -f vllm-deepseek-32b-lws.yaml
The deployment will start immediately, but the pod might remain in ContainerCreating state for several minutes (5–15 minutes) while it pulls the large GPU-enabled container image. After the container starts, it will take additional time (10–15 minutes) to download and load the DeepSeek model.You can monitor the progress with the following code:
# Monitor pod status
kubectl get pods

# Check pod logs
kubectl logs -f <pod-name>
Here is the out put of one of the pods
Kubectl logs -f vllm-deepseek-32b-lws-0
The following is the expected output when pods are running:
NAME                      READY   STATUS    RESTARTS   AGE
vllm-deepseek-32b-lws-0  1/1     Running   0          10m
vllm-deepseek-32b-lws-0-1  1/1     Running   0          10m
We also deploy an ingress resource that configures the ALB to route traffic to our vLLM service:
# Apply the ingress (only after the controller is running)
kubectl apply -f vllm-deepseek-32b-lws-ingress.yaml
You can check the status of the ingress with the following code:
# Check ingress status
kubectl get ingress
The following is an example of the expected output:
NAME                       CLASS   HOSTS   ADDRESS                                                                  PORTS   AGE
vllm-deepseek-32b-lws-ingress  alb     *       k8s-default-vllmdeep-xxxxxxxx-xxxxxxxxxx.us-west-2.elb.amazonaws.com     80      5m
Test the deployment
When the deployment is complete, we can test our vLLM server. It provides the following API endpoints:
/v1/completions – For text completions
/v1/chat/completions – For chat completions
/v1/embeddings – For generating embeddings
/v1/models – For listing available models
# Test the vLLM server
# Get the ALB endpoint
export VLLM_ENDPOINT=$(kubectl get ingress vllm-deepseek-32b-lws-ingress -o jsonpath='{.status.loadBalancer.ingress[0].hostname}')
echo "vLLM endpoint: $VLLM_ENDPOINT"

# Test the completions API
curl -X POST http://$VLLM_ENDPOINT/v1/completions \
  -H "Content-Type: application/json" \
  -d '{
      "model": "deepseek-ai/DeepSeek-R1-Distill-Qwen-32B",
      "prompt": "Hello, how are you?",
      "max_tokens": 100,
      "temperature": 0.7
  }'
The following is an example of the expected output:
{
  "id": "cmpl-xxxxxxxxxxxxxxxxxxxxxxxx",
  "object": "text_completion",
  "created": 1717000000,
  "model": "deepseek-ai/DeepSeek-R1-Distill-Qwen-32B",
  "choices": [
    {
      "index": 0,
      "text": " I'm doing well, thank you for asking! How about you? Is there anything I can help you with today?",
      "logprobs": null,
      "finish_reason": "length",
      "stop_reason": null,
      "prompt_logprobs": null
    }
  ],
  "usage": {
    "prompt_tokens": 5,
    "total_tokens": 105,
    "completion_tokens": 100
  }
}
You can also test the chat completions API:
# Test the chat completions API
curl -X POST http://$VLLM_ENDPOINT/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
      "model": "deepseek-ai/DeepSeek-R1-Distill-Qwen-32B",
      "messages": [{"role": "user", "content": "What are the benefits of using FSx Lustre with EKS?"}],
      "max_tokens": 100,
      "temperature": 0.7
  }'
If you encounter errors, check the logs of the vLLM pods:
# Troubleshooting
kubectl logs -f <pod-name>
Performance considerations
In this section, we discuss different performance considerations.
Elastic Fabric Adapter
EFA provides significant performance benefits for distributed inference workloads:
Reduced latency – Lower and more consistent latency for communication between GPUs across nodes
Higher throughput – Higher throughput for data transfer between nodes
Improved scaling – Better scaling efficiency across multiple nodes
Better performance – Significantly improved performance for distributed inference workloads
FSx for Lustre integration
Using FSx for Lustre for model storage provides several benefits:
Persistent storage – Model weights are stored on the FSx for Lustre file system and persist across pod restarts
Faster loading – After the initial download, model loading is much faster
Shared storage – Multiple pods can access the same model weights
High performance – FSx for Lustre provides high-throughput, low-latency access to the model weights
Application Load Balancer
Using the AWS Load Balancer Controller with ALB provides several advantages:
Path-based routing – ALB supports routing traffic to different services based on the URL path
SSL/TLS termination – ALB can handle SSL/TLS termination, reducing the load on your pods
Authentication – ALB supports authentication through Amazon Cognito or OIDC
AWS WAF – ALB can be integrated with AWS WAF for additional security
Access logs – ALB can log the requests to an Amazon Simple Storage Service (Amazon S3) bucket for auditing and analysis
Clean up
To avoid incurring additional charges, clean up the resources created in this post. Run the provided ./cleanup.sh script to clean the Kubernetes resources (ingress, LeaderworkerSet, PersistentVolumeClaim, PersistentVolume, AWS Load Balancer Controller, and storage class), IAM resources, the FSX for Lustre file system, and the EKS cluster:
chmod +x cleanup.sh
./cleanup.sh
For more detailed cleanup instructions, including troubleshooting CloudFormation stack deletion failures, refer to the README.md file in the GitHub repository.
Conclusion
In this post, we demonstrated how to deploy the DeepSeek-R1-Distill-Qwen-32B model on Amazon EKS using vLLMs, with GPU support, EFA, and FSx for Lustre integration. This architecture provides a scalable, high-performance system for serving LLM inference workloads.AWS Deep Learning Containers for vLLM provide a streamlined, optimized environment that simplifies LLM deployment by minimizing the complexity of environment configuration, dependency management, and performance tuning. By using these preconfigured containers, organizations can reduce deployment timelines and focus on deriving value from their LLM applications.By combining AWS DLCs with Amazon EKS, P4d instances with NVIDIA A100 GPUs, EFA, and FSx for Lustre, you can achieve optimal performance for LLM inference while maintaining the flexibility and scalability of Kubernetes.This solution helps organizations:
Deploy LLMs efficiently at scale
Optimize GPU resource utilization with container orchestration
Improve networking performance between nodes with EFA
Accelerate model loading with high-performance storage
Provide a scalable, high performance inference API
The complete code and configuration files for this deployment are available in our GitHub repository. We encourage you to try it out and adapt it to your specific use case.
MCP (Model Control Protocol) is a protocol designed to standardize interactions with Generative AI models, making it easier to build and manage AI applications. It provides a consistent way to communicate context with different types of models, regardless of where they’re hosted or how they’re implemented. The protocol helps bridge the gap between model deployment and application development by providing a unified interface for model interactions. While this protocol provides flexibility in tool choice, there are key challenges when the order of tool usage needs to be enforced. In this blog post, you will learn about how I designed this functionality and implemented it into the AWS Cloud Control API (CCAPI) MCP server .
The Challenge – Enforcing Tool Ordering in MCP
When you think of MCP, you likely think of choice. Arguably one of the main reasons you may want to use an MCP server, is to allow a Large Language Model (LLM) (through agents) to access a set of tools such as reading from a database, sending an email, or in something along those lines. The MCP framework doesn’t provide a native mechanism to enforce the sequence in which tools must be called.
Let’s take as an example two tools – fetch_weather_data() and send_email(). For the LLM using your MCP server, it is reasonable to think that you may want to enforce that an email that is sent has the current weather included. Or for another example, tools getOrderId() and getOrderDetail(), where the OrderId would be required to subsequently fetch the OrderDetail. Since MCP currently lacks tool ordering preferences, these types of sequential dependencies can be challenging to enforce.
MCP tools are designed to be independent functions that an LLM can invoke as needed. There’s no built-in concept of “workflow” or “sequence” in the MCP framework itself. Each tool call is treated as a separate operation, with no inherent knowledge of what came before or what should come after. This means that by default, an LLM can technically call your tools in any order it chooses, regardless of the logical workflow you intend.
While LLMs excel at flexible decision-making, some scenarios like infrastructure management require strict operational ordering. This presents a unique challenge when building MCP servers: how do you maintain the LLM’s natural flexibility while enforcing critical sequential dependencies?
When you think of Infrastructure as Code (IaC), you think of repeatability, consistency, versioning, and continuous integration/continuous deployment (CI/CD). Within CI/CD you have a set flow:
Pull request is generated
CI/CD pipeline is triggered
Series of steps runs to run linting, security tests, unit tests, end-to-end tests, etc.
A failure in any stage should stop the entire pipeline run
This posed a challenge with IaC and LLMs. Generative AI is non-deterministic, meaning the same prompt may not always generate the same exact response. If the result deviates significantly from what it should be, it is considered a hallucination. So, what can be done to guide the LLM on what you want it to do? Let’s talk about how this was addressed in the CCAPI MCP server.
Understanding MCP Tool Discovery and Initialization
Before diving into the solution, it’s important to understand how MCP servers communicate with AI Agents. During initialization, the MCP protocol follows specific lifecycle phases where capabilities and tools are discovered.
The Model Context Protocol defines a structured lifecycle for client-server connections that ensures proper capability negotiation and state management.
These phases include:
Initialization: Capability negotiation and protocol version agreement
Operation: Normal protocol communication
Shutdown: Graceful termination of the connection
The initialization phase establishes protocol compatibility and shares implementation details. This is when an AI Agent learns about available tools through schema definitions and receives instructions for tool usage. This initialization process is crucial to the solution, as it’s where AI Agents first discover what tools are available and how they should be used. During this phase, the client sends information about its protocol version, capabilities, and implementation details. This is how tools like Amazon Q CLI receive information about an MCP server’s version, available tools, and usage instructions.
Note: For more information on the MCP lifecycle, see these docs.
Solution – Token-Based Tool Orchestration: A New Pattern for AI Agents in MCP
MCP presents a specific challenge: tools cannot directly communicate with each other to enforce execution order. The CCAPI MCP server addresses this through a token messenger pattern shown above, where the server generates and controls validation tokens, and the AI Agent (as the MCP client) passes these tokens between tool calls.
Core Implementation:
Function Enhancement – The mcp.tool() decorator transforms each function into a more capable entity. It wraps the function with a schema that defines required inputs and their validation rules, while preserving detailed documentation through docstrings. Each enhanced function clearly communicates its requirements and provides explicit error messages when dependencies aren’t met.
Dependency Discovery – During the initialize phase in the MCP lifecycle, the AI Agent (as the MCP client) receives a complete map of all defined tools and their schemas from the MCP server. The LLM, which is part of the AI Agent, uses these schemas to understand dependencies through both parameter descriptions and required input arguments. For instance, when a tool requires a parameter described as “Result from get_aws_session_info()” and defines security_scan_token as a required input argument, the LLM understands it needs both valid tokens before proceeding. This combination of descriptive text and explicit input requirements enables the AI Agent to execute sequences like get_aws_session_info() → generate_infrastructure_code() → run_checkov() → create_resource().
Token Validation Control –The server generates and controls all workflow tokens through a unified server-side storage system (_workflow_store). Each tool in the workflow generates cryptographically secure tokens, and these tokens are stored server-side with their associated data.
The AI Agent maintains these tokens in its conversation context throughout the workflow, passing them between tool calls. For security, each token used by the AI Agent must be validated against the server’s token storage. Since these tokens are short-lived, they are stored in memory (RAM) and are actively managed by the MCP server, which deletes tokens after use to maintain freshness. Any remaining tokens are automatically cleared when the server process ends or restarts. If a token doesn’t exist in the server’s storage (either because it’s invalid or already consumed), the operation fails immediately with an error. This validation is uniform across all token types, ensuring the AI Agent cannot create or modify tokens.
As the workflow progresses, tools consume existing tokens and generate new ones. For example, when explain() receives a properties_token, it first validates it exists and matches what is in _workflow_store, then consumes it and generates a new explained_properties_token. This creates a cryptographically secure chain of operations that enforces the workflow sequence (generate → scan → create), with server-side validation at every step.
The result is a predictable workflow system with strong security controls – tokens must be generated by the server and validated against server-side storage at each step, helping ensure the integrity of the infrastructure management process. This approach provides robust workflow enforcement within the confines of the current functionality of the FastMCP framework. While explicit schema-defined dependencies like @mcp.tool(depends_on=["run_checkov"]) as mentioned in this GitHub Issue would be ideal and could hopefully be added in future FastMCP versions, the current token-based approach with descriptive parameter names and clear validation provides reliable tool ordering that LLMs consistently follow without confusion.
Potential Limitations and Solutions
Session Management – When an AI Agent’s session ends or refreshes, any in-progress workflows must be restarted. This is by design – tokens are meant to be short-lived and tied to specific workflow sequences. AWS credentials naturally expire within hours as part of standard security practices, providing a natural boundary for workflow sessions.
Concurrent Workflows – Each AI Agent interaction operates independently, which is appropriate for maintaining security boundaries between different workflow instances. While this means each session starts fresh, it ensures clean separation between different infrastructure operations.
Implementation Options – For organizations requiring workflow persistence, traditional database storage could maintain session state between restarts. However, since tokens are designed to be short-lived security controls, most implementations can rely on the default in-memory storage with natural session boundaries.
The token messenger pattern provides a solid foundation for secure workflow orchestration, with its intentionally ephemeral tokens ensuring proper tool sequencing and data integrity during infrastructure operations.
The Future of MCP
While the above solution works, this process made me think about the future of MCP and how it can and should continue to grow. There are many updates to the framework I’ve seen recently, and it’s great to see activity. For Agentic AI in general, there are strong signs that the future of agentic platforms may be more deterministic in nature, as highlighted by Claude Code’s new support for lifecycle hooks. Per their docs, “Hooks provide deterministic control over Claude Code’s behavior, ensuring certain actions always happen rather than relying on the LLM to choose to run them.” For IaC and other deterministic technologies that it is desired to integrate AI with, this is essential for wide-scale adoption.
Conclusion
The journey of Model Control Protocol (MCP) and this new frontier of leveraging AI for managing cloud infrastructure continues to evolve, presenting both opportunities and challenges in the world of cloud computing and artificial intelligence. Current approaches using prompt loading and parameter dependencies have helped address initial challenges around tool ordering and security protocols, demonstrating how MCP can be effectively used in enterprise applications.
While the current implementation using workflow tokens and validation checks provides a functional solution, we continue to explore ways to enhance the protocol’s capabilities. For those interested in contributing to MCP’s evolution, you can find our proposals for protocol improvements, including enhanced dependency management, in the modelcontextprotocol GitHub org as well as in the FastMCP GitHub repository.
If you’d like to learn more about the AWS Cloud Control API MCP server mentioned in this blog, check out the documentation and GitHub repo. If you’d like to get hands on with it and other AWS MCP servers, check out this AWS workshop. Happy vibe coding my friends.
Recent security research has highlighted the importance of CI/CD pipeline configurations, as documented in AWS Security Bulletin AWS-2025-016. This post pulls together existing guidance and recommendations into one guide.
Continuous integration and continuous deployment (CI/CD) practices help development teams deliver software efficiently and reliably. AWS CodeBuild provides managed build services that integrate with source code repositories like GitHub, GitLab, and other Source Control Management (SCM) systems. While this guide uses GitHub examples, the security principles and webhook configuration approaches apply to other supported source control systems.
However, certain configurations require careful attention. We strongly recommend that you do not use automatic pull request builds from untrusted repository contributors without proper security controls and a clear understanding of your threat model. This configuration allows untrusted code to execute in your build environment with access to repository credentials and environment variables. Webhook configurations determine which repository events trigger builds and what code gets executed during the build process. Understanding these configurations is essential for maintaining appropriate security boundaries while preserving the automation benefits that make CI/CD valuable.
Security teams and DevOps engineers can use these practical approaches to configure AWS CodeBuild to meet their security goals while maintaining development velocity. We’ll explore webhook configurations, trust boundaries, and implementation strategies that emphasize threat model assessment, least-privilege access, and proactive monitoring of your pipeline configurations.
Security of the pipeline implications
Under the shared responsibility model, while AWS manages the security of the underlying AWS CodeBuild infrastructure, customers are responsible for securing their pipeline configurations, access controls, and the code that runs within their build environments. This shared responsibility is critical when considering the security of the pipeline itself.
When AWS CodeBuild processes pull requests automatically, it builds the code in an environment with access to repository credentials, environment variables, and potentially sensitive information. This creates specific security of the pipeline considerations:
Repository access: AWS CodeBuild projects require repository credentials to read source code and create webhooks. These credentials provide specific permissions that vary based on your configuration.
Build execution: The build process runs the retrieved source code, which may include build scripts, dependency definitions, or test files from pull requests.
Build environment: AWS CodeBuild environments may have access to environment variables, AWS credentials, or other configuration data needed for the build process.
Establishing trust boundaries
Effective security of the pipeline starts with clearly defining trust boundaries for different types of code contributions:
Internal contributors: Team members with repository write access who have been verified through your organization’s access management processes.
External contributors: Contributors from outside your organization who submit pull requests from forked repositories.
Automated processing: Code that runs without manual review as part of the build process.
These trust boundaries form the foundation for threat modeling your specific environment. Internal and trusted environments can often rely more heavily on automation with contributor filtering and least-privilege controls. Public and open source projects require more stringent controls due to the inherent risks of processing untrusted contributions – these environments benefit from stricter webhook filtering, comprehensive approval gates, or the self-hosted GitHub Actions runner approach discussed later.
The key principle is finding the appropriate balance between security controls and development velocity based on your specific risk profile and contributor trust levels. With these considerations in mind, let’s examine how to assess and configure your current AWS CodeBuild webhook settings.
Configuring secure webhooks
Webhooks represent the preferred mechanism by which external events trigger AWS CodeBuild processes. When properly configured, webhooks provide a powerful and efficient way to automate your build processes in response to repository changes. However, improper webhook configuration can create security vulnerabilities by allowing untrusted code to execute in privileged environments.The security of your webhook configuration depends on understanding exactly which events trigger builds, what level of access those builds have, and what code gets executed during the build process. This section provides a comprehensive approach to authoring, assessing, configuring, and maintaining secure webhook configurations.
Assessing current webhook configurations
Begin by reviewing your existing AWS CodeBuild projects to understand their current webhook configurations. The following AWS CLI commands provide a systematic approach to gathering this information:
# List all CodeBuild projects in your region
aws codebuild list-projects --region us-west-2

# Retrieve detailed configuration for analysis
aws codebuild batch-get-projects --region us-west-2 \
  --names $(aws codebuild list-projects --region us-west-2 \
  --query 'projects[*]' --output text | tr '\n' ' ')
When you run these commands, pay particular attention to the webhook section in the output. This section contains the filterGroups configuration, which determines exactly which repository events trigger builds.
Now that you understand how to review your current setup, let’s examine common configuration patterns and their security implications.
Webhook configuration patterns
Understanding common webhook configuration patterns helps you quickly identify potential security concerns and implement appropriate improvements. The following patterns represent different approaches to webhook configuration, each with specific security implications.
Note: These patterns are not recommended for use and are shown here to help you identify configurations that may need attention.
This configuration allows contributors who can create a pull request to trigger code execution in your build environment. We strongly recommend that you do not use automatic pull request builds from untrusted repository contributors.
Configuration requiring immediate review – No event filtering
Without filtering, this configuration can trigger builds for a wide variety of repository events.
Recommended secure webhook configurations
The following configurations represent security best practices that balance automation benefits with appropriate security controls. These patterns help to reduce security risks while maintaining the development velocity that makes CI/CD valuable.
Push-based builds (Recommended for most use cases)
Push-based builds make sure that only users with repository write access can trigger builds, which means contributors have already been vetted through your repository’s access control mechanisms.
Organizations that rely heavily on external open-source contributions may find this approach too restrictive. For example, a popular open-source project that receives dozens of pull requests daily from external contributors would need to manually merge each contribution before builds can run, significantly slowing down the contribution review process. In such cases, contributor-filtered builds or the self-hosted GitHub Actions runner approach may be more appropriate.
Contributor-filtered builds (Recommended for trusted contributors only)
This configuration allows pull request builds from specific, trusted contributors.
Important: Filtering applies to the GitHub account ID, not repository ownership. Contributors working from forked repositories can still introduce untrusted code that executes in your build environment.
Before implementing these configurations in your environment, consider these key factors that will help facilitate a smooth transition.
Webhook configuration implementation steps
While implementing the webhook security measures below, consider these broader practices:
Threat modeling: Assess your specific risk profile before selecting approaches.
Infrastructure as code: Use Infrastructure as Code (IaC) tools for production implementations.
Gradual implementation: Implement changes incrementally with observation periods.
Testing and rollback: Validate changes in non-production environments first.
The following implementation approach moves from most restrictive to more automated configurations. Choose the approach that best fits your organization’s risk tolerance and operational requirements. This three-step process moves from the most restrictive approach to more automated configurations while maintaining security controls. Each step builds upon the previous one, creating layers of security that work together to protect your pipeline.
Note: The following examples use the AWS CLI for demonstration purposes. Similar configuration steps can be performed using the AWS Management Console through the AWS CodeBuild project settings.
Step 1: Configure push-only builds
Push-based builds help make sure that only verified contributors can trigger builds. This approach is more secure, because contributors must already be vetted through your repository’s access control mechanisms before they can push code. Configure your webhook to trigger only on push events:
Branch-based filtering adds an additional layer of security by making sure that builds are triggered only for changes to specific branches. This approach recognizes that not all branches in a repository have the same security requirements or risk profiles.
For example, changes to main or production branches typically require more stringent security controls than changes to feature or development branches. By implementing branch-based filtering, you can apply appropriate security measures based on the criticality and exposure of different branches.
Contributor filtering can be used to manage pull request builds by allowing automation for trusted contributors while requiring manual review for others. This approach recognizes that different contributors represent different risk profiles and should be treated accordingly.
The first step in implementing contributor filtering is identifying the GitHub user IDs of your trusted contributors.
Retrieve GitHub user IDs for trusted contributors:
Important: Contributor allowlists require ongoing maintenance as team membership changes. Consider using Infrastructure as Code templates like the Cloudformation examples to manage webhook configurations and contributor lists in version control.
Webhook filtering provides the first layer of security by controlling which events trigger builds. However, comprehensive pipeline security requires additional controls around the permissions and credentials available to those builds once they execute. The following section covers how to implement defense-in-depth security through proper access controls and credential management.
Access control and credential management
This section covers specific approaches to limit the permissions available to build processes, scope repository access tokens appropriately, and create isolated environments that help contain potential security issues. These practices work together to implement defense-in-depth security while maintaining the operational benefits of automated CI/CD workflows.
Implementing least-privilege access
AWS CodeBuild projects require IAM service roles to access AWS resources during the build process. The principle of least privilege dictates that each role should have only the minimum permissions necessary to perform its intended function. By creating separate, purpose-built IAM roles for different types of builds, you can help reduce the potential impact of unauthorized access to build environments.
The following examples demonstrate how to structure minimal IAM roles for different build scenarios. These examples serve as starting points that you should customize based on your specific requirements, adding only the permissions your builds actually need.
Service role configuration
Create minimal IAM roles that provide only the permissions required for specific build types:
Leveraging IAM Access Analyzer for CodeBuild security
AWS IAM Access Analyzer can generate least-privilege policies for your AWS CodeBuild service roles based on actual CloudTrail activity from your build executions. This eliminates guesswork by analyzing the specific AWS API calls your builds make, rather than requiring you to predict what permissions might be needed.
After running your CodeBuild projects for a representative period, use Access Analyzer’s policy generation feature to create refined policies. This approach proves particularly valuable for complex build processes where the required permissions might not be immediately obvious.
When processing external contributions, the principle of least privilege becomes important for repository access tokens. If an unauthorized user gains access to a token through an untrusted build, properly scoped tokens limit the potential impact to only the permissions necessary for the build process.
Configure fine-grained GitHub Personal Access Tokens with minimal permissions to help reduce this risk. Even if accessed inappropriately, a properly scoped token can only read source code (already accessible through the PR) and write status messages – it cannot push code, modify repository settings, or access other repositories.
The following permissions represent the minimum required access for processing external pull requests, demonstrating how to limit token scope to only essential operations:
contents:read – Read-only access to repository source code (already accessible through the PR)
statuses:write – Write commit status messages only (cannot modify code or settings)
metadata:read – Access basic repository information (name, description, public status)
Important: Use fine-grained personal access tokens restricted to the target repository only. Otherwise, this could allow access to other repositories beyond what is necessary for the build process.
This scoped approach ensures that even if a token is accessed inappropriately, the potential impact is limited to reading already-accessible information and writing status messages. The token cannot push code, modify repository settings, create webhooks, or access other repositories.
Credential storage and rotation
The following examples demonstrate how to securely store and reference these tokens using AWS Secrets Manager. AWS Secrets Manager provides automatic rotation capabilities, encryption at rest and in transit, and fine-grained access controls that help prevent tokens from being exposed in build logs or configuration files. This approach also enables centralized token management across multiple CodeBuild projects while maintaining audit trails of token access.
The centralized storage enables credential rotation capabilities, helping to minimize the window of exposure compared to hardcoded tokens that would require infrastructure updates to rotate.
Build environment isolation
Establishing proper build environment security controls helps maintain pipeline integrity. The foundation of this approach involves implementing separation between test and release builds, which helps prevent credential escalation and limits the scope of potential unauthorized access.
Network isolation represents another layer of protection. Configure VPC settings specifically for builds that process external code by creating dedicated security groups with carefully restricted outbound access. These security groups should permit only necessary connections, such as HTTPS traffic for downloading legitimate dependencies, while blocking unnecessary network access that could be exploited by untrusted code.
Update your AWS CodeBuild projects to leverage this network isolation through proper VPC configuration, including specified subnets and the restricted security groups you’ve established.
Multi-stage pipeline security with human review gates
Implementing security controls across multiple pipeline stages helps provide proper validation and approval processes, especially when processing external contributions. This approach combines automated scanning with human oversight to identify issues before they reach production.
Code inspection integration
Configure your build specification to automatically run security tools like Automated Security Helper during the build process. These tools scan for code security issues and dependency problems, generating detailed reports for review.
Structure the build to continue execution even when issues are found, allowing all scans to complete while automatically failing builds that contain security problems requiring attention. Store all scan artifacts to provide security teams with detailed information for approval decisions.
Manual approval gates
After code passes automated security scans, configure manual approval gates to involve human reviewers for final validation. This helps provide appropriate human review before proceeding to sensitive environments.
The access control and credential management practices outlined in this section provide specific, actionable approaches to implementing defense-in-depth security for AWS CodeBuild pipelines. These controls work together to create multiple layers of protection while maintaining the operational benefits that make CI/CD automation valuable.
Alternative approach – Self-hosted GitHub Actions runners
AWS CodeBuild’s self-hosted GitHub Actions runner capability addresses the configuration issues described in this guide by isolating repository credentials from the build environment and using GitHub Actions’ execution framework instead of AWS CodeBuild webhook processing.
For organizations that need to process external contributions automatically, configure runners with proper access controls, use ephemeral runners to minimize persistent access, and apply standard security practices for runner management.
The security controls outlined in previous sections provide protection at build time, but comprehensive defense-in-depth security requires ongoing visibility into your pipeline activities and configuration changes. Monitoring and compliance tracking serve as the final layer of your security framework, helping you detect configuration drift, audit access patterns, and maintain security posture over time.
AWS CloudTrail provides detailed logging of API calls made to AWS services, including AWS CodeBuild. Enable CloudTrail logging to create a comprehensive audit trail of all build-related activities in your environment.
AWS Config tracks AWS CodeBuild project configurations over time, providing an inventory of projects and a complete history of configuration changes. This includes webhook modifications, resource relationships, and compliance tracking across your environment. Configure AWS Config to monitor AWS CodeBuild projects and receive notifications when security-critical configurations like webhook filters are modified. For more information, see the AWS Config sample with CodeBuild documentation.
Conclusion
Implementing defense-in-depth security for AWS CodeBuild pipelines requires layered controls that address different security considerations. The most effective approach combines webhook filtering, access controls, credential management, and monitoring to provide comprehensive protection. By implementing these layered practices outlined in this guide, you can maintain development velocity while establishing robust pipeline security. Key principles to remember:
Assess your threat model first – different projects require different security approaches
Establish clear trust boundaries between different types of contributors
Use webhook filtering to control when builds are triggered
Implement least-privilege access for build environments
Monitor and audit configurations regularly using AWS Config and CloudTrail
Store secrets in AWS Secrets Manager or SSM Parameter Store and enable rotation
AWS CodeBuild provides the flexibility to implement these security measures while maintaining the operational benefits that make pipelines valuable. Apply the configurations and mitigations in this guide based on your specific risk profile and operational requirements. Regular review and updates of your configurations will help your pipelines remain secure as your organization’s needs evolve.
Stay tuned for additional practical guides for implementing CI/CD security best practices. If you have questions or feedback about this post, including suggestions for topics that would help you most, start a new thread on re:Post : Begimher or contact AWS Support.
Databases and query engines, including Amazon Redshift, often rely on different statistics about the underlying data to determine the most effective way to execute a query, such as the number of distinct values and which values have low selectivity. When Amazon Redshift receives a query, such as
SELECT insert_date, sum(sales)
FROM receipts
WHERE insert_date BETWEEN '2024-12-01' AND '2024-12-31'
GROUP BY insert_date
, the query planner uses statistics to make an educated guess on the most effective method to load and process data from storage. More statistics about the underlying data can often help a query planner select a plan that leads to the best query performance, but this can require a tradeoff among the cost of computing, storing, and maintaining statistics, and might require additional query planning time.
Data lakes are a powerful architecture to organize data for analytical processing, because they let builders use efficient analytical columnar formats like Apache Parquet, while letting them continue to modify the shape of their data as their applications evolve with open table formats like Apache Iceberg. One challenge with data lakes is that they don’t always have statistics about their underlying data, making it difficult for query engines to determine the optimal execution path. This can lead to issues, including slow queries and unexpected changes in query performance.
In 2024, Amazon Redshift customers queried over 77 EB (exabytes) of data residing in data lakes. Given this usage, the Amazon Redshift team works to innovate on data lake query performance to help customers efficiently access their open data to get near real-time insights to make critical business decisions. In 2024, Amazon Redshift launched several features that improve query performance for data lakes, including faster query times when a data lake doesn’t have statistics. With Amazon Redshift patch 190, the TPC-DS 3TB benchmark showed an overall 2x query performance improvement on Apache Iceberg tables without statistics, including TPC-DS Query #72, which improved by 125 times from 690 seconds to 5.5 seconds.
In this post, we first briefly review how planner statistics are collected and what impact they have on queries. Then, we discuss Amazon Redshift features that deliver optimal plans on Iceberg tables and Parquet data even with the lack of statistics. Finally, we review some example queries that now execute faster because of these latest Amazon Redshift innovations.
Prerequisites
The benchmarks in this post were run using the following environment:
Now, let’s review how database statistics work and how they impact query performance.
Overview of the impact of planner statistics on query performance
To understand why database are statistics are important, first let’s review what a query planner does. A query planner is the brain of a database: when you send a query to a database, the query planner must determine the most efficient way to load and compute all of the data required to answer the query. Having information about the underlying dataset, such as statistics about the number of rows in a dataset, or the distribution of data, can help the query planner generate an optimal plan for retrieving the data. Amazon Redshift uses statistics about the underlying data in tables and columns statistics to determine how to build an optimal query execution path.
Let’s see how this works in an example. Consider the following query to determine the top five sales dates in December 2024 for stores in North America:
SELECT insert_date, sum(sales) AS total_sales
FROM receipts
JOIN stores ON stores.id = receipts.store_id
WHERE
  stores.region = 'NAMER' AND
  receipts.insert_date BETWEEN '2024-12-01' AND '2024-12-31'
GROUP BY receipts.insert_date
ORDER BY total_sales DESC
LIMIT 5;
In this query, the query planner has to consider several factors, including:
Which table is larger, stores or receipts? Am I able to query the smaller table first to reduce the amount of searching on the larger table?
Which returns more rows, receipts.insert_date BETWEEN '2024-12-01' AND '2024-12-31' or stores.region = 'NAMER'?
Is there any partitioning on the tables? Can I search over a smaller set of data to speed up the query?
Having information about the underlying data can help to generate an optimal query plan. For example, stores.region = 'NAMER' might only return a few rows (that is, it’s highly selective), meaning it’s more efficient to execute that step of the query first before filtering through the receipts table. What helps a query planner make this decision is the statistics available on columns and tables.
Table statistics (also known as planner statistics) provide a snapshot of the data available in a table to help the query planner make an informed decision on execution strategies. Databases collect table statistics through sampling, which involves reviewing a subset of rows to determine the overall distribution of data. The quality of statistics, including the freshness of data, can significantly impact a query plan, which is why databases will reanalyze and regenerate statistics after a certain threshold of the underlying data changes.
Amazon Redshift supports several table and column level statistics to assist in building query plans. These include:
Statistic
What it is
Impact
Query plan influence
Number of rows (numrows)
Number of rows in a table
Estimates the overall size of query results and JOIN sizes
Decisions on JOIN ordering and algorithms, and resource allocation
Number of distinct values (NDV)
Number of unique values in a column
Estimates selectivity, that is, how many rows will be returned from predicates (for example, WHERE clause) and the size of JOIN results
Decisions on JOIN ordering and algorithms
NULL count
Number of NULL values in a column
Estimates number of rows eliminated by IS NULL or IS NOT NULL
Decisions on filter pushdown (that is, what nodes execute a query) and JOIN strategies
Min/max values
Smallest and largest values in a column
Helps range-based optimizations (for example, WHERE x BETWEEN 10 AND 20)
Decisions on JOIN order and algorithms, and resource allocation
Column size
Total size of column data in memory
Estimates overall size of scans (reading data), JOINs, and query results
Decisions on JOIN algorithms and ordering
Open formats such as Apache Parquet don’t have any of the preceding statistics by default and table formats like Apache Iceberg have a subset of the preceding statistics such as number of rows, NULL count and min/max values. This can make it challenging for query engines to plan efficient queries. Amazon Redshift has added innovations that improve overall query performance on data lake data stored in Apache Iceberg and Apache Parquet formats even when all or partial table or column-level statistics are unavailable. The next section reviews features in Amazon Redshift that help improve query performance on data lakes even when table statistics aren’t present or are limited.
Amazon Redshift features when data lakes don’t have statistics for Iceberg tables and Parquet
As mentioned previously, there are many cases where tables stored in data lakes lack statistics, which creates challenges for query engines to make informed decisions on selecting the best query plan. However, Amazon Redshift has released a series of innovations that improve performance for queries on data lakes even when there aren’t table statistics available. In this section, we review some of these enhancements and how they impact your query performance.
Dynamic partition elimination through distributed joins
Dynamic partition elimination is a query optimization technique that allows Amazon Redshift to skip reading data unnecessarily during query execution on a partitioned table. It does this by determining which partitions of a table are relevant to a query and only scanning those partitions, significantly reducing the amount of data that needs to be processed.
For example, imagine a schema that has two tables:
sales (fact table) with columns:
sale_id
product_id
sale_amount
sale_date
products (dimension table) with columns:
product_id
product_name
category
The sales table is partitioned by product_id. In the following example, you want to find the total sales amount for products in the Electronics category in December 2024.
SQL query:
SELECT SUM(s.sale_amount)
FROM sales s
JOIN products p ON s.product_id = p.product_id
WHERE p.category = 'Electronics';
How Amazon Redshift improves this query:
Filter on dimension table:
The query filters the products table to only include products in the Electronics category.
Identify relevant partitions:
With the new improvements, Amazon Redshift analyzes this filter and determines which partitions of the sales table need to be scanned.
It looks at the product_id values in the products table that match the Electronics category and only scans those specific partitions in the sales table.
Instead of scanning the entire sales table, Amazon Redshift only scans the partitions that contain sales data for electronics products.
This significantly reduces the amount of data Amazon Redshift needs to process, making the query faster.
Previously, this optimization was only applied on broadcast joins when all child joins below the join were also broadcast joins. The Amazon Redshift team extended this capability to work on all broadcast joins, regardless if the child joins below them are broadcast. This allows more queries to benefit from dynamic partition elimination, such as TPC-DS Q64 and Q75 for Iceberg tables, and TPC-DS Q25 in Parquet.
Metadata caching for Iceberg tables
The Iceberg open table format employs a two-layer structure: a metadata layer and a data layer. The metadata layer has three levels of files (metadata.json, manifest lists, and manifests), which allows for performance features such as faster scan planning and advanced data filtering. Amazon Redshift uses the Iceberg metadata structure to efficiently identify the relevant data files to scan, using partition value ranges and column-level statistics and eliminating unnecessary data processing.
The Amazon Redshift team observed that Iceberg metadata is frequently fetched multiple times both within and across queries, leading to potential performance bottlenecks. We implemented an in-memory LRU (least recently used) cache for parsed metadata, manifest list files, and manifest files. This cache keeps the most recently used metadata so that we avoid fetching them repeatedly from Amazon Simple Storage Service (Amazon S3) across queries. This caching has helped with overall performance improvements of up to 2% in a TPC-DS 3TB workload. We observe more than 90% cache hits for these metadata structures, reducing the iceberg metadata processing times considerably.
Stats inference for Iceberg tables
As mentioned previously, the Apache Iceberg file format comes with some statistics such as number of rows, number of nulls, column min/max values and column storage size in the metadata files called manifest files. However, they don’t always provide all the statistics that we need especially average width which is important for the cost-based optimizer used by Amazon Redshift.
We delivered a feature to estimate average width for variable length columns such as string and binary from Iceberg metadata. We do this by using the column storage size and the number of rows, and we adjust for column compression when necessary. By inferring these additional statistics, our optimizer can make more accurate cost estimates for different query plans. This stats inference feature, released in Amazon Redshift patch 186, offers up to a 7% improvement in the TPC-DS benchmarks. We have also enhanced Amazon Redshift optimizer’s cost model. The enhancements include planner optimizations that improve the estimations of the different join distribution strategies to take into account the networking cost of distributing the data between the nodes of an Amazon Redshift cluster. The enhancements also include improvements to Amazon Redshift query optimizer. These enhancements, which are a culmination of several years of research, testing, and implementation demonstrated up to a 45% improvement in a collection of TPC-DS benchmarks.
Example: TPC-DS benchmark highlights on Amazon Redshift no stats queries on data lakes
One way to measure data lake query performance for Amazon Redshift is using the TPC-DS benchmark. The TPC-DS benchmark is a standardized benchmark designed to test decision support systems, specifically looking at concurrently accessed systems where queries can range from shorter analytical queries (for example, reporting, dashboards) to longer running ETL-style queries for moving and transforming data into a different system. For these tests, we used the Cloud Data Warehouse Benchmark derived from the TPC-DS 3TB to align our testing with many common analytical workloads, and provide a standard set of comparisons to measure improvements to Amazon Redshift data lake query performance.
We ran these tests across data stored both in the Apache Parquet data format, in addition to Apache Iceberg tables with data in Apache Parquet files. Because we focused these tests on out-of-the-box performance, none of these data sets had any table statistics available. We performed these tests using the specified Amazon Redshift patch versions in the following table, and used Amazon Redshift Serverless with 88 RPU without any additional tuning. The following results represent a power run, which is the sum of how long it took to run all the tests, from a warm run, which are the results of the power run after at least one execution of the workload:
P180 (12/2023)
P190 (5/2025)
Apache Parquet (only numrows)
7,796
3,553
Apache Iceberg (out-of-the-box, no tuning)
4,411
1,937
We saw notable improvements in several query run times. For this post, we focus on the improvements we saw in query 82:
SELECT
    i_brand_id brand_id, i_brand brand,
    sum(ss_ext_sales_price) ext_price
FROM date_dim, store_sales, item
WHERE d_date_sk = ss_sold_date_sk AND
    ss_item_sk = i_item_sk AND
    i_manager_id = 83 AND
    d_moy = 12 AND
    d_year = 2002
GROUP BY i_brand, i_brand_id
ORDER BY ext_price desc, i_brand_id
LIMIT 100;
In this query, we’re searching for the top 100 selling brands from a specific manager in December 2002, which represents a typically dashboard-style analytical query. In our power run, we saw a reduction in query time from 512 seconds to 18.1 seconds for Apache Parquet data, or a 28.2x improvement in performance. The accelerated query performance for this query in a warm run is due to the improvements to the cost-based optimizer and dynamic partition elimination.
If you ran these tests on your own and don’t need the resources anymore, you’ll need to delete your Amazon Redshift Serverless workgroup. See Shutting down and deleting a cluster. If you don’t need to store the Cloud Data Warehouse Benchmark data in your S3 bucket anymore, see Deleting Amazon S3 objects.
Conclusion
In this post, you learned how cost-based optimizers for databases work, and how statistical information about your data can help Amazon Redshift execute queries more efficiently. You can optimize query performance for Iceberg tables by automatically collecting Puffin statistics, which lets Amazon Redshift use these recent innovations to more efficiently query your data. Giving more info to your query planner—the brain of Amazon Redshift—helps to provide more predictable performance and helps you to further scale how you interact with your data in your data lakes and data lakehouses.
About the authors
Martin Milenkoski is a Software Development Engineer on the Amazon Redshift team, currently focusing on data lake performance and query optimization. Martin holds an MSc in Computer Science from the École Polytechnique Fédérale de Lausanne.
Kalaiselvi Kamaraj is a Sr. Software Development Engineer on the Amazon Redshift team. She has worked on several projects within the Amazon Redshift Query processing team and currently focusing on performance related projects for Amazon Redshift DataLake and query optimizer.
Jonathan Katz is a Principal Product Manager – Technical on the AWS Analytics team and is based in New York. He is a Core Team member of the open-source PostgreSQL project and an active open-source contributor, including to the pgvector project.
AWS Certificate Manager (ACM) simplifies the provisioning, management, and deployment of public and private TLS certificates for AWS services and your on-premises and hybrid applications. To further enhance the flexibility of ACM for diverse workloads, we’re introducing a powerful new capability: ACM exportable public certificates. You can use this capability to export public TLS certificates and associated private keys from ACM, which can be used to secure workloads on Amazon Elastic Compute Cloud (Amazon EC2) instances, Amazon Elastic Kubernetes Service (Amazon EKS) pods, on-premises servers, or servers hosted with other cloud providers. The capability supports public certificates that are newly created in your AWS account
In this post, we show you how to automate the export and distribution of public exportable certificates across a diverse infrastructure. We walk you through creating workflows that automatically deliver certificates to multiple destinations including EC2 instances and virtual machines in hybrid environments. We explore how this automation works, its benefits, and provide a step-by-step guide to get started. Additionally, we explore how you can use integration with Amazon EventBridge to trigger automatic certificate exports when certificates are issued or renewed, streamlining certificate deployment across heterogeneous environments and significantly reducing management overhead.
Background: ACM and certificate management
ACM is a managed service that removes the complexity of purchasing, uploading, and renewing TLS certificates. It provides public certificates at no additional cost for AWS services integrated with ACM such as Elastic Load Balancing (ELB), Amazon CloudFront, and Amazon API Gateway. ACM also supports importing third-party public certificates and issuing private certificates through AWS Private Certificate Authority. Prior to this release, ACM public certificates were designed for AWS services integrated with ACM such as CloudFront, providing seamless TLS encryption for those services. For use cases involving third-party content delivery networks (CDNs) or workloads terminating TLS on EC2 instances, customers typically sourced certificates from other providers or imported them into ACM for centralized management. Customers have told us that they would like to use ACM for these use cases, extending its simplicity and scalability to a wider range of environments. The new ACM exportable public certificates capability fulfills this need, enabling you to export ACM-managed public certificates for use with your custom workloads while maintaining centralized management and automated renewals.
With ACM you can now request a public certificate, validate domain ownership, and export the certificate for use with software that terminates TLS such as Apache, NGINX, or Microsoft IIS. ACM handles certificate renewals, reducing the risk of expirations that can disrupt your applications.
How it works: ACM public certificate issuance and renewal
To use ACM exportable public certificates, you need to understand how to automate certificate management using the issuance and renewal processes. In this section, we describe these processes and their automation capabilities, which are critical for deploying and maintaining certificates.
ACM public certificate issuance
Issuing an ACM public certificate involves the following steps:
Request a certificate: In the AWS Management Console for ACM, or the AWS Command Line Interface (AWS CLI) or API, initiate a certificate request by specifying the domain names you want to secure (for example, example.com or *.example.com).
Validate domain ownership: ACM requires that you prove control over the domain. If the domain is hosted on Amazon Route 53, you can request that ACM validate the domain ownership. For domains hosted outside AWS, you can use DNS validation (adding a CNAME record) or email validation (responding to emails sent to domain contacts).
Certificate issuance: After the domain ownership has been validated, ACM issues the certificate, which includes the public key, private key, and certificate chain.
Associate the certificate with an integrated AWS service: See Services integrated with ACM for information about associating the certificate with an integrated AWS service.
Export the certificate: With the new capability you can now export the public certificate, private key, and certificate chain using the ACM console, AWS CLI, or API for use on servers that aren’t integrated with ACM.
Bind to application: Install the exported certificate on your server (for example, Apache or NGINX) to enable TLS termination.
With the launch of this new capability, you can now control the future exportability of public certificates that you create in ACM.
To create an exportable public certificate, use the ACM console to create a new public certificate. To get started, choose Request certificate in the ACM console and on the Request public certificate page, under Allow export, select Enable export. If you select Disable export, the private key for this certificate will be disallowed for exporting from ACM, which cannot be changed after certificate issuance.
Figure 1: Request a public certificate and enable export
After creating your certificate with the Enable export option selected and completing domain ownership validation, you can proceed with the export process, as shown in Figure 2. To export your certificate, select it from the list of certificates, choose More actions, and select Export.
Figure 2: Export a certificate
ACM public certificate renewal
ACM automates the process of certificate renewal, which includes:
Renewal initiation: ACM automatically initiates renewal 60 days before a certificate expires.
Domain revalidation: ACM revalidates domain ownership using the same method as the initial issuance (DNS or email).
Certificate update: Upon successful revalidation, ACM issues a new certificate with the same Amazon Resource Name (ARN) with updated validity dates.
When a certificate is renewed in ACM, the service automatically sends an EventBridge event to notify you that the new certificate is available. If the renewal fails, ACM sends notifications to both the AWS Health Dashboard and EventBridge. To stay informed about these certificate events, you can create EventBridge rules that monitor for specific certificate-related events. You can configure these rules to send notifications to an Amazon Simple Notification Service Amazon (SNS) topic so that interested parties receive timely updates about their certificate status.
New EventBridge schema fields: Following successful ACM certificate renewal, the ACM Certificate Available event now includes an exportable field that indicates with TRUE|FALSE whether the public certificate is ready to be exported.
Export and update: You can export the renewed certificate and update it on your servers manually or using EventBridge targets such as AWS Systems Manager Automation documents triggered by EventBridge rules. For more information, see Event bus targets in Amazon EventBridge.
You can use EventBridge rules to monitor specific events and route them to one or more targets (such as Amazon SNS topics, AWS Lambda functions, or other AWS services) for processing. For example, when domain validation fails because of DNS configuration issues, ACM generates an ACM Certificate Renewal Action RequiredEventBridge event. By creating an EventBridge rule that targets an SNS topic, you can subscribe to receive email alerts and take necessary corrective actions.
Automating deployment of renewed certificates using EventBridge
The certificate renewal process helps make sure that your TLS certificates remain valid without manual intervention, but updating certificates across diverse environments can still require effort. When ACM renews a certificate, it generates an EventBridge event. You can configure EventBridge rules to trigger targets based on this event, such as:
Send notifications: Route the event to Amazon SNS to send email or SMS notifications to administrators.
Automate certificate deployment: Trigger Lambda functions or Systems Manager Automation documents to retrieve the renewed certificate using the ACM API and update it on your servers.
Monitor renewal failures: Configure alerts based on ACM certificate renewal failure events. These events can be directly routed to notification channels to inform you about issues such as domain validation errors.
To set this up, create an EventBridge rule to match the ACM renewal event, specify a target, (such as an SNS topic or Lambda function). This automation minimizes manual intervention, helping to facilitate seamless certificate updates across your infrastructure.
Solution overview
In the section, we describe two workflows. The first demonstrates an automated process for exporting existing ACM public certificates and installing them on target EC2 instances or virtual machines. The second workflow is triggered when public certificates are automatically renewed by ACM when they become available in ACM, followed by updating these certificates on downstream EC2 instances and virtual machines. While this solution uses EC2 instances and virtual machines as the target systems, the same methods can be applied to refresh public certificates at scale across various types of systems.
Prerequisites
To extend this automated public certificate export and update process to:
Add TargetTagKey tags to EC2 instances and virtual machines where you want to deploy renewed certificates. The automation uses these tags to identify target instances.
The ExportCertificate API requires a certificate passphrase for operation. To maintain security best practices, we recommend storing passwords in encrypted form using password vaults instead of plain text storage. Our implementation uses AWS Secrets Manager to securely store these sensitive credentials. The solution also uses Amazon DynamoDB to maintain certificate metadata, which includes a reference to the corresponding secret name stored in Secrets Manager. For added security, the DynamoDB table’s data is automatically encrypted at rest using AWS Key Management Service (AWS KMS).
ACM certificate export
Figure 3: ACM certificate issuance and export workflow
The workflow shown in Figure 3 demonstrates an automated process for exporting existing public ACM certificates through an API-driven process and deploying them to downstream systems.
The process begins when a user makes a request to an API Gateway endpoint, providing essential parameters including the CertificateArn to identify the certificate you want to export, CertName for certificate identification, and TargetTagKey and TargetTagValue for identifying the target EC2 instances where you want this certificate to be installed. The following is an example of the payload sent to API Gateway:
Upon receiving the request, API Gateway triggers an AWS Step Functions workflow containing multiple orchestrated states.
The initial state executes a Lambda function named acm-Export, which generates a passphrase for the private key.
The acm-Export lambda function also securely stores the generated passphrase in Secrets Manager and uses the generated passphrase to export the ACM certificate.
After completing the acm-Export function, the Step Functions workflow invokes the Lambda ssm-run function.
This function performs two operations: it checks the certificate’s existence in DynamoDB (which serves as an inventory tracking system) and manages record-keeping. When the function encounters an existing certificateARN, it updates the record with the current CertExpiryDate and LastExportedDate timestamp values. For certificates being exported for the first time, the Lambda function creates a new record in DynamoDB if no matching entry exists. This new record captures the certificate’s metadata, including its details and tracking information. Figure 4 shows how this metadata is structured in a DynamoDB table entry in the console.
Figure 4: Certificate metadata in a DynamoDB table
Following the metadata verification step in DynamoDB, the Lambda function also initiates running a custom Systems Manager document called Install-ACMCertificate. This document handles the installation of newly exported public certificates onto specified EC2 instances. The same Systems Manager document can be used for certificate installation or updates onto on-premises servers, providing flexibility in certificate deployment.
When the Systems Manager document execution succeeds, it deploys the newly exported public certificates to EC2 instances matching the TargetTagKey. By default, on Linux servers, certificates are stored in /etc/ssl/certs and /etc/ssl/private, though these paths can be customized in the Systems Manager document.
After successfully running this Systems Manager document, the Step Functions workflow then advances to its next state, which triggers another Lambda function named Statuscheck. This function monitors the execution status of the previously initiated Systems Manager document. The Step Functions workflow concludes its execution after it confirms the successful installation of certificates on the targeted EC2 instances.
ACM certificate renewal and export
Figure 5: ACM certificate and renewal process
When a certificate is within 60 days of expiring, ACM automatically begins the renewal process. When ACM successfully completes a certificate renewal, it generates an event in EventBridge as shown in the following example:
The workflow illustrated in Figure 5 showcases an automated system for exporting existing public ACM certificates using an API-driven process and deploying them to downstream systems.
The solution uses an EventBridge rule that watches for certificate renewal notifications and triggers the acm-renew Lambda function in response. The function begins its execution by receiving the certificate ARN from the ACM event. Using this ARN as a lookup key, it queries a DynamoDB table to retrieve the associated certificate metadata. From this query, it extracts essential certificate details including the Certificate Name and the TargetTag Key-Value pairs that identify which resources need the updated certificate. These details are needed for the subsequent certificate deployment process and help make sure that the updates are applied to the correct systems.
This information is then formatted into a payload and used to trigger a Step Functions workflow. This Step Functions workflow follows the same process described in the ACM Certificate Export section.
Steps 3 through 9 follow the process described in the ACM Certificate Export section. Upon successful completion of step 9, the Step Functions workflow concludes its execution. At this point, the renewed public certificate has been successfully installed on the targeted EC2 instances, completing the automated certificate export and installation process.
Detailed instructions for downloading the solution, executing it, validating the certificate export, and deploying it to your AWS account are available on GitHub.
Pricing and availability
ACM exportable public certificates are available in AWS commercial Regions, AWS GovCloud (US) Regions, and China Regions and follow a pay-as-you go pricing model, with no upfront commitments. You pay only for the certificates you export. Public certificates for AWS Services integrated with ACM such as ELB, CloudFront, and API Gateway remain available at no additional cost. For detailed pricing, see AWS Certificate Manager pricing.
Conclusion
The ACM exportable public certificates capability empowers customers to secure diverse workloads with a unified, managed certificate solution. By enabling certificate exports for EC2, containers, on-premises servers and other cloud providers, ACM simplifies TLS management, while offering centralized control, automated renewals and cost-effective pricing. Get started today by exploring this feature in the ACM console and streamline your certificate management workflows.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
As the capabilities of quantum computing evolve, AWS is committed to helping our customers stay ahead of emerging threats to public-key cryptography. Today, we’re announcing the integration of FIPS 204: Module-Lattice-Based Digital Signature Standard (ML-DSA) into AWS Key Management Service (AWS KMS). Customers can now create and use ML-DSA keys through the same familiar AWS KMS APIs they use today for digital signatures, including CreateKey, Sign, and Verify operations. This new feature is generally available and you can use ML-DSA in the following AWS Regions: US West (N. California), and Europe (Milan) with the remaining commercial Regions to follow in the coming days. This launch is part of our broader AWS post-quantum cryptography migration plan, which we covered in our recent blog post. In this post, we guide you through creating ML-DSA keys and post-quantum signatures with AWS KMS.
Many organizations use AWS KMS to cryptographically sign firmware, operating systems, applications, or other artifacts. With ML-DSA support in AWS KMS, you can now generate and use post-quantum keys for signing operations within FIPS-140-3 Level 3 certified HSMs. By implementing ML-DSA signatures now, you can help make sure that your systems remain secure throughout their operational lifetime, even if cryptographically relevant quantum computers become available. This is especially important for manufacturers who install long-lived roots of trust during production—whether embedded directly in hardware or in devices that might remain offline for extended periods. In both cases, cryptographic signatures cannot be easily updated after deployment, making post-quantum readiness critical for the entire operational lifetime of these systems.
What’s new
AWS KMS offers three new AWS KMS key specs: ML_DSA_44, ML_DSA_65, and ML_DSA_87, which you can use with the new post-quantum SigningAlgorithmML_DSA_SHAKE_256. Like our other signing algorithms, this name includes the hash function that’s used within the signature scheme to digest messages before signing or verification. In this case, the hash function used is SHAKE256—part of the SHA-3 family of hash functions standardized by NIST in FIPS 202.
Table 1 shows the details for each key spec, including their NIST security categories and corresponding key sizes in bytes. Each ML-DSA key spec represents a balance between security strength and resource requirements. ML-DSA-44 is suitable for applications requiring security comparable to classical 128-bit encryption, while ML-DSA-65 and ML-DSA-87 provide progressively stronger security levels equivalent to classical 192-bit and 256-bit encryption, respectively. As you move up in security levels, you’ll notice corresponding increases in key and signature sizes, enabling you to choose the key spec that best matches your security needs and engineering constraints.
Key spec
NIST security Level
Public key (B)
Private key (B)
Signature (B)
ML_DSA_44
1 (equivalent to 128-bit security)
1312
2560
2420
ML_DSA_65
3 (equivalent to 192-bit security)
1952
4032
3309
ML_DSA_87
5 (equivalent to 256-bit security)
2592
4896
4627
When using the AWS KMS Sign API with a RAW MessageType, the message to be signed is limited to 4096 bytes. For messages larger than 4096 bytes, pre-processing the message outside of AWS KMS to create what’s known as µ (mu) is required to generate a smaller-sized message input to the KMS Sign API. This external mu process pre-digests the message using the public key of the ML-DSA signing key pair to create a message size of 64 bytes. To support this launch, we’ve added a new message type in the KMS Sign API—EXTERNAL_MU—that can be used with ML-DSA signing or verification calls to indicate when a message has been pre-processed using µ (mu) before submitted to AWS KMS.
In the following sections, we include more information about constructing external mu and demonstrate basic AWS KMS operations with ML-DSA. We cover key creation, signature generation and verification, and both RAW and EXTERNAL_MU signing modes. Note that the produced RAW or EXTERNAL_MU ML-DSA signatures are identical when the same message and signing key are used.
Make note of the KeyId or Arn value from the response; you’ll need this to reference your key in subsequent signing operations. The response confirms that the creation of an ML_DSA_65 key configured for SIGN_VERIFY operations, which will use the ML_DSA_SHAKE_256 signing algorithm for signature operations.
Signing
In this section, we include some examples of ML-DSA signing and verifying a JSON Web Token (JWT) commonly used to transfer claims between parties for web authorization. In 2021, we described how to sign and verify JWTs with Elliptic Curve Digital Signature Algorithm (ECDSA), a classic asymmetric cryptographic algorithm (see How to verify AWS KMS signatures in decoupled architectures at scale). In the following examples, the token is instead signed with an ML-DSA private key managed by AWS KMS and verified either within AWS KMS or externally using OpenSSL.
The JWT content to be signed is from section 3.1 of RFC7519. More specifically, the JWT header is:
Note that the following examples output the ML-DSA signature produced on the message by using the ML-DSA private key managed by AWS KMS in a binary format. You need to convert them to Base64URL to use them in JWT, but various data encryption and signing formats can use these signatures. These include Cryptographic Message Syntax (CMS), CBOR Object Signing and Encryption (COSE), or image signing encodings for UEFI and Open Titan. While converting between binary and these formats is straightforward, support for the new algorithms might not be available in common cryptographic implementations of these signing formats at the time of this writing.
RAW ML-DSA signing (no external mu)
To sign a message of less than 4096 bytes in AWS KMS with ML-DSA, you can use the AWS CLI:aws kms sign \
Make sure to replace the target-key-id value of <1234abcd-12ab-34cd-56ef-1234567890ab> with your KeyId. This command will produce a signature and write it to disk as ExampleSignature.bin.
After producing the signature, you can create the complete JWT (consisting of header, payload, and signature) with a single command:
This command will output a ready-to-use JWT in the format required by RFC 7519 and signed using AWS KMS:
eyJ0eXAiOiJKV1QiLA0KICJhbGciOiJNTC1EU0EtNjUifQ.eyJpc3MiOiJqb2UiLA0KICJleHAiOjE3NDg5NTIwMDAsDQogImh0dHA6Ly9leGFtcGxlLmNvbS9pc19yb290Ijp0cnVlfQ.<base64url of the signature as per RFC7519>
External mu ML-DSA signing
Note that AWS KMS imposes a 4096-byte limit on the size of the raw message when using the Sign API to minimize the latency of the response. In cases where the message to be signed is larger than 4096 bytes or if pre-digesting the external mu has performance advantages you need, you must use the EXTERNAL_MU message type instead of RAW in AWS KMS.
Before using the EXTERNAL_MU message type with the AWS KMS Sign API, you must locally perform a pre-hash calculation on your message. So, first, retrieve the public key from AWS KMS, and convert it to DER format using the following command (replace the example key ID with a valid key ID from your AWS account):
In this example, set the domain separator value and context length as zero; this sets the context used in the signature as the empty string, which is the default.
Hash the public key then prepend it to the message prefix: (SHAKE256(pk) || M’).
Hash to produce a 64-byte mu: Mu = SHAKE256(SHAKE256(pk) || M’)
You can use a single OpenSSL 3.5 command to construct the digest:
Now you can call AWS KMS to sign the 64-byte digest to produce the ML-DSA signature in file ExampleSignature.bin, making sure to set the MessageType to EXTERNAL_MU:
The final signed JWT token is identical to the one produced previously in RAW mode.
Signature verification using AWS KMS
In this section, we show you how to verify ML-DSA signatures using AWS KMS or locally in your own environment. We assume that you have an ML-DSA signature in ExampleSignature.bin, produced on the JWT content with the private key in AWS KMS and identified with KEY_ARN.
Note that, although the following examples demonstrate signature verification using public keys directly from AWS KMS, these same principles extend to certificate-based systems, such as a private PKI, in which public keys are embedded in end-entity certificates (of the signer). In such scenarios, verifiers would first verify the identity of the signer by validating the certificate chain ties to a trusted root, then use the public key of the end-entity certificate to verify the ML-DSA signature of the content. The IETF is standardizing ML-DSA for use in X.509 certificates through RFC draft draft-ietf-lamps-dilithium-certificates.
RAW ML-DSA verification
To verify the signature using AWS KMS, you can call the following command, replacing the example key-id with the same one you used to sign.
The verification result is stored in the SignatureValid field.
External mu ML-DSA verification
If you have the external mu digest of the JWT content in mu.bin along with the signature and the corresponding keypair in AWS KMS, you can use the digest without having access to the entire message or calculating the digest again.
If you want to reduce AWS KMS API consumption costs and better control the use of API quotas while keeping the security of AWS KMS-generated and stored keys for ML-DSA signature generation, you can verify ML-DSA signatures locally, outside of AWS KMS.
In this example, you use OpenSSL 3.5 to verify the signature in ExampleSignature.bin. You first must fetch the DER-encoded public key from AWS KMS in file public_key.der as shown in the External mu ML DSA signing section. OpenSSL 3.5 can then verify the signature on the message by using the public key.
Today’s launch of ML-DSA support in AWS KMS marks an important milestone in our commitment to post-quantum cryptography. With three different security levels of ML-DSA in both raw and external digest modes, you have flexible options to meet your security requirements while preparing for the quantum computing era. The seamless integration with existing AWS KMS APIs makes it straightforward to incorporate quantum-resistant signatures into your applications today. This implementation is particularly valuable if you need to:
Meet FIPS 140-3 compliance requirements when using post-quantum cryptography.
Sign code, artifacts, documents or other data that need to remain trusted and verifiable for many years into the future, including the period after cryptographically relevant quantum computers exist.
Start post-quantum cryptography testing as part of your application development process using a cryptographic service such as AWS KMS that has previously been approved for use.
Managing and scaling data streams efficiently is a cornerstone of success for many organizations. Apache Kafka has emerged as a leading platform for real-time data streaming, offering unmatched scalability and reliability. However, setting up and scaling Kafka clusters can be challenging, requiring significant time, expertise, and resources. This is where Amazon Managed Streaming for Apache Kafka (Amazon MSK) Express brokers come into play.
Express brokers are a new broker type in Amazon MSK that are designed to simplify Kafka deployment and scaling.
In this post, we walk you through the implementation of MSK Express brokers, highlighting their core features, benefits, and best practices for rapid Kafka scaling.
Key features of MSK Express brokers
MSK Express brokers revolutionize Kafka cluster management by delivering exceptional performance and operational simplicity. With up to three times more throughput per broker, Express brokers can sustainably handle an impressive 500 MBps ingress and 1000 MBps egress on m7g.16xl instances, setting new standards for data streaming performance.
Their standout feature is their fast scaling capability—up to 20 times faster than standard Kafka brokers—allowing rapid cluster expansion within minutes. This is complemented by 90% faster recovery from failures and built-in three-way replication, providing robust reliability for mission-critical applications.
Express brokers eliminate traditional storage management responsibility by offering unlimited storage without pre-provisioning, while simplifying operations through preconfigured best practices and automated cluster management. With full compatibility with existing Kafka APIs and comprehensive monitoring through Amazon CloudWatch and Prometheus, MSK Express brokers provide an ideal solution for organizations seeking a highly-performant and low-maintenance data streaming infrastructure.
Comparison with traditional Kafka deployment
Although Kafka provides robust fault-tolerance mechanisms, its traditional architecture, where brokers store data locally on attached storage volumes, can lead to several issues impacting the availability and resiliency of the cluster. The following diagram compares the deployment architecture.
The traditional architecture comes with the following limitations:
Extended recovery times – When a broker fails, recovery requires copying data from surviving replicas to the newly assigned broker. This replication process can be time-consuming, particularly for high-throughput workloads or in cases where recovery requires a new volume, resulting in extended recovery periods and reduced system availability.
Suboptimal load distribution – Kafka achieves load balancing by redistributing partitions across brokers. However, this rebalancing operation can strain system resources and take considerable time due to the volume of data that must be transferred between nodes.
Complex scaling operations – Expanding a Kafka cluster requires adding brokers and redistributing existing partitions across the new nodes. For large clusters with substantial data volumes, this scaling operation can impact performance and require significant time to complete.
MSK Express brokers offers fully managed and highly available Regional Kafka storage. This significantly decouples compute and storage resources, addressing the aforementioned challenges and improving the availability and resiliency of Kafka clusters. The benefits include:
Faster and more reliable broker recovery – When Express brokers recover, they do so in up to 90% less time than standard brokers and place negligible strain on the clusters’ resources, which makes recovery faster and more reliable.
Efficient load balancing – Load balancing in MSK Express brokers is faster and less resource-intensive, enabling more frequent and seamless load balancing operations.
Faster scaling – MSK Express brokers enable efficient cluster scaling through rapid broker addition, minimizing data transfer overhead and partition rebalancing time. New brokers become operational quickly due to accelerated catch-up processes, resulting in faster throughput improvements and minimal disruption during scaling operations.
Scaling use case example
Consider a use case requiring 300 MBps data ingestion on a Kafka topic. We implemented this using an MSK cluster with three m7g.4xlarge Express brokers. The configuration included a topic with 3,000 partitions and 24-hour data retention, with each broker initially managing 1,000 partitions.
To prepare for anticipated midday peak traffic, we needed to double the cluster capacity. This scenario highlights one of Express brokers’ key advantages: rapid, safe scaling without disrupting application traffic or requiring extensive advance planning. During this scenario, the cluster was actively handling approximately 300 MBps of ingestion. The following graph shows the total ingress on this cluster and the number of partitions it is holding across three brokers.
The scaling process involved two main steps:
Adding three additional brokers to the cluster, which completed in approximately 18 minutes
Using Cruise Control to redistribute the 3,000 partitions evenly across all six brokers, which took about 10 minutes
As shown in the following graph, the scaling operation completed smoothly, with partition rebalancing occurring rapidly across all six brokers while maintaining uninterrupted producer traffic.
Notably, throughout the entire process, we observed no disruption to producer traffic. The entire operation to double the cluster’s capacity was completed in just 28 minutes, demonstrating MSK Express brokers’ ability to scale efficiently with minimal impact on ongoing operations.
Best practices
Consider the following guidelines to adopt MSK Express brokers:
When implementing new streaming workloads on Kafka, select MSK Express brokers as your default option. If uncertain about your workload requirements, begin with express.m7g.large instances.
Use the Amazon MSK sizing tool to calculate optimal broker count and type for your workload. Although this provides a good baseline, always validate through load testing that simulates your real-world usage patterns.
Choose larger instance types for high-throughput workloads. A smaller number of large instances is preferable to many smaller instances, because fewer total brokers can simplify cluster management operations and reduce operational overhead.
Conclusion
MSK Express brokers represent a significant advancement in Kafka deployment and management, offering a compelling solution for organizations seeking to modernize their data streaming infrastructure. Through its innovative architecture that decouples compute and storage, MSK Express brokers deliver simplified operations, superior performance, and rapid scaling capabilities.
The key advantages demonstrated throughout this post—including 3 times higher throughput, 20 times faster scaling, and 90% faster recovery times—make MSK Express brokers an attractive option for both new Kafka implementations and migrations from traditional deployments.
As organizations continue to face growing demands for real-time data processing, MSK Express brokers provide a future-proof solution that combines the reliability of Kafka with the operational simplicity of a fully managed service.
Masudur Rahaman Sayem is a Streaming Data Architect at AWS with over 25 years of experience in the IT industry. He collaborates with AWS customers worldwide to architect and implement sophisticated data streaming solutions that address complex business challenges. As an expert in distributed computing, Sayem specializes in designing large-scale distributed systems architecture for maximum performance and scalability. He has a keen interest and passion for distributed architecture, which he applies to designing enterprise-grade solutions at internet scale.
Generative AI applications often involve a combination of various services and features—such as Amazon Bedrock and large language models (LLMs)—to generate content and to access potentially confidential data. This combination requires strong identity and access management controls and is special in the sense that those controls need to be applied on various levels. In this blog post, you will review the scenarios and approaches where you can apply least privilege access to applications using Amazon Bedrock. To fully benefit from the guidance in this post, you need an understanding of AWS APIs, AWS Identity and Access Management (IAM) policies, and AWS security services.
Let’s start by defining the principle of least privilege (PoLP): The PoLP is a security concept that advises granting the minimal level of access—or permissions—necessary for users, programs, or systems to perform their tasks. The main idea is that the fewer permissions an entity has, the lower the risk of malicious or accidental damage. Applying the PoLP to your use of AWS serves two purposes:
Security: By limiting access, you reduce the potential impact of a security incident. If a user or service has minimal permissions, the scope for any damage can be significantly reduced.
Operational simplicity: Managing permissions can become complex if not properly managed and maintained. Applying the PoLP to your access controls early helps keep configurations as manageable as possible. Finally, there are regulatory frameworks that require separation of duty between roles and a documented strategy for access controls, which can be achieved in part by adhering to the PoLP.
Amazon Bedrock is a fully managed AWS service that makes high-performing foundation models (FMs) available through a single unified API. You use Amazon Bedrock through AWS APIs, which expose actions for the control plane and administration such as the configuration of Amazon Bedrock Guardrails and Amazon Bedrock Agents, in addition to data plane functional actions such as inference.
Generally, the path to using Amazon Bedrock for a production workload includes the following stages:
Model selection: Decide on the required features (Retrieval Augmented Generation (RAG), fine-tuning, and so on), evaluate and select a model, and approve a EULA if necessary.
Model adaptation: Prompt engineering, integration of Amazon Bedrock into the application, and addition of model customization if desired.
Model testing: Validate and test the solution.
Model operation: Deploy the solution and make it available. Monitor and operate the solution.
In the following sections, we go through each phase and outline how you can apply the PoLP.
Model selection
In this phase, you choose the features and models that are needed to fulfill your requirements and define how you will apply the PoLP. These can include, for example, model customization, Retrieval Augmented Generation (RAG) or the use of agents.
Security should be integrated into the design so that the defined controls can be implemented during the development phase. One approach to define the necessary security controls is threat modeling. Doing this exercise early in the process will simplify the upcoming phases. The results can be used later to decide on the required guardrails, potential changes to the architecture, and test cases.
In this phase, you will also decide how the solution should be deployed. Customers typically operate in a multi-account setup; therefore, the selection of target organizational units (OUs) and accounts is required. We recommend creating a new OU for generative AI applications. For details, see the deep-dive chapter on generative AI in the AWS Security Reference Architecture. We will talk later about service control policies (SCPs) and how they can be used to restrict permissions. The generative AI OU is a good place to enforce those guardrails.
Amazon Bedrock provides access to a variety of high-performing FMs from leading AI companies such as AI21 Labs, Anthropic, Cohere, Meta, Mistral AI, Stability AI, and Amazon. In this stage, you need to choose the models that you’ll use and approve them. With a third-party FM, approval might include accepting a EULA. You can limit identities and the models that they can subscribe to in order to follow compliance with EULAs that have been reviewed by your legal department. The following is an example of an SCP that allows account operators to enable all Anthropic FMs and a single Meta Llama FM.
While this approach works well if you’re only allowlisting actions, you might have highly privileged users that already have broad access to AWS Marketplace APIs. In such a case, you can follow a deny all except a few approach. Such a policy, using the same models as before, would look like the following example:
In this phase, the solution is built—that is, code is written. This is mostly identical to traditional software development, however there are some areas specific to generative AI, such as prompt engineering, prompt guardrails, model monitoring, and agent design. In this post, we focus solely on the identity and access management aspects.
Adaptation is the phase where the detailed permission sets are created. Data perimeters can be used as a conceptual tool to define and implement guardrails. Because data perimeters are typically coarse grained, they aren’t sufficient to achieve the goal of the PoLP. However, in combination with fine-grained policies, they support a defense-in-depth approach. The following data perimeters exist:
Identity: Only trusted identities are allowed in my network, only trusted identities can access my resources.
Resource: My identities can access only trusted resources, only trusted resources can be accessed from my network.
Network: My identities can access resources only from expected networks, my resources can only be accessed from expected networks.
For applications that use Amazon Bedrock, you can use a virtual private cloud (VPC) network construct with Amazon Virtual Private Cloud (Amazon VPC) to host them. Doing so means that you can then use AWS PrivateLink to create VPC endpoints for both data and control plane APIs. Using PrivateLink to create endpoints, it’s possible to provide access to Amazon Bedrock for VPC-bound compute resources (such as Amazon Elastic Compute Cloud (Amazon EC2), or AWS Lambda) without the need for an internet gateway. In other words, you can deploy these resources entirely in private subnets. By using resource-based policies on these endpoints, you can restrict the principals, actions, resources, and conditions related to making API calls.
Let’s assume you have a VPC with an EC2 instance running in a private subnet hosting an application that uses Amazon Bedrock model invocations and have created an interface VPC endpoint to connect to the Amazon Bedrock data plane. The EC2 instance is configured to use an instance profile using the <rolename> IAM role and needs to be able to invoke a single Anthropic’s Claude Instant FM through an Amazon Bedrock InvokeModel API call. You can apply the PoLP to the containing VPC, and thus the EC2 instance, with a custom policy on the Amazon Bedrock interface VPC endpoint. To use the following policy in your own account, replace the default interface VPC endpoint policy with the following example, replacing <rolename> with the role you want to allow and <account-id> with your 12-digit account number.
You can define the allowed models that can be used in Amazon Bedrock directly in the policy. However, if you have multiple applications that use Amazon Bedrock, you might have to update multiple policies when a new model is allowed to be used. To complement the data perimeter approach, you can add an SCP to limit the models that can be used for inference. Because Amazon Bedrock is using a simple API (InvokeModel and Converse) for inference, a condition element in an IAM policy can be used to deny the use of unapproved models. Note that while the two policies (the SCP and the VPC endpoint policy) look similar, they work differently: VPC endpoint policies are enforced provided that the network path through PrivateLink is enforced; SCPs are applied to principals within the account or OU they’re attached to. Be extra careful if the calling identity resides outside of your account, because only the VPC endpoint policy will apply.
For example, imagine that you wanted to block the invocation of all Anthropic FMs across your organizations within AWS Organizations, in all AWS Regions. The following SCP example applied to the OUs or AWS accounts in scope would achieve that outcome:
A solution built on Amazon Bedrock might include model customization. The common denominator of the different customization approaches is that they include data, which is assumed to be confidential and thus in-scope for applying the PoLP. Here, we take a scenario where data is stored in Amazon S3 and can be encrypted using a customer managed AWS Key Management Service (AWS KMS) key.
Measures can be taken on multiple levels, as conceptualized in data perimeters: network, identity, and resource. Amazon Bedrock model customization uses service roles, which allows you to apply fine-grained and least-privilege access end-to-end. These service roles will be assumed by the Amazon Bedrock service principal, so that it can execute actions on your behalf. To allow the Amazon Bedrock service principal to assume the role in your account, you need to attach a trust policy to the role.
Let’s imagine that you’re running an Amazon Bedrock customization job in the us-east-1 (N. Virginia) Region. Using the following trust policy example will allow only the Amazon Bedrock service principal to assume your role.
Make sure to replace <account-id> in the preceding example trust policy with your own 12-digit account number. The policy contains a condition that provides cross-service confused deputy prevention by adding the aws:SourceAccount condition. The confused deputy problem is a situation where an entity that doesn’t have permission to perform an action can coerce a more privileged entity to perform the action. In AWS, cross-service impersonation can result in the confused deputy problem. Cross-service impersonation can occur when one service (the calling service) calls another service (the called service). AWS provides tools to help you protect your data for all services with service principals that have been given access to resources in your account. Both the aws:SourceArn and aws:SourceAccount global condition context keys in the role’s trust policy limit the permissions that Amazon Bedrock gives another service (in the preceding case, to the customization job) to the resource. aws:SourceArn is the more restrictive approach here, because it defines the specific source of the assume request, and not just the AWS account.
You should provide only the permissions that are required to fulfill the model customization task. For example, imagine that you want to limit access to your training data, the validation data bucket, and the output bucket (where Amazon Bedrock will deliver output metrics). The following policy, attached to that same service role, provides only those permissions. Replace the <training-bucket> placeholder with the bucket name that contains your training data, <validation-bucket> with your validation bucket, and <output-bucket> with the bucket where you want to store metrics.
Complementing this approach, we recommend using a VPC for the model customization job to restrict access to the training data. Technically, this again involves a VPC endpoint resource policy because the network is using interface VPC endpoints to access your S3 bucket. This allows you to define another network control, specifically an S3 bucket policy that only allows access through a specific VPC endpoint. So, for the situation where you want to limit access for the customization job itself, you can apply a bucket policy such as the following example, replacing <training-bucket> with the bucket name that contains your training data, and <vpce-id> with the ID of the VPC endpoint that resides in your VPC:
In addition, you would restrict the principals that can access your VPC endpoint and the actions they’re allowed to take in Amazon S3. For simplicity, we’re omitting an example policy here because it’s very similar to the one we have in the Amazon Bedrock invocation section earlier in this post.
If you need to enforce encryption in Amazon S3 using a customer managed AWS KMS key (SSE-KMS), you will need to do the following:
Update the bucket policy with a statement denying unencrypted content being uploaded.
Update the KMS key policy to allow the service role to decrypt and describe the key.
The next policy example should be added to the bucket policy and demonstrates how to deny unencrypted objects being added to an S3 bucket. Again, replace <training-bucket> with the name of the S3 bucket that contains your training data:
Finally, in the KMS key policy, you need a statement similar to the following to allow the Amazon Bedrock service role access to the KMS key. Replace <account-id> with your 12-digit account number and <bedrock-service-role> with the role you created, which will be assumed by the Amazon Bedrock service principal. Make sure to only give the required access to decrypt data with the KMS key to the IAM role:
Amazon Bedrock can also encrypt a customized model with a customer managed KMS key. Amazon Bedrock uses KMS key grants to encrypt the customized model and to decrypt it later when you deploy it for inference. Therefore, you need to grant the same IAM role permissions to create KMS key grants in the KMS key policy. The KMS key you use for this purpose is typically different than the one you used to encrypt the training data to allow fine-grained permissions on both keys.
So, let’s imagine that you want to use two different roles to encrypt and decrypt the customized models. To allow the role that executes the model customization job to use your KMS key, you need to add the following policy statements to the KMS key policy, replacing <account-id> with your 12-digit account number, <region> with the Region where you run Amazon Bedrock, <bedrock-model-customization-role> with the role name you use to run the model customization job, and <invocation-role> with the name of the role you use for inference.
By using KMS key grants, you can revoke the permissions you granted to the service role after the customization job is done, thus reducing the permissions to least privilege. Also, Amazon Bedrock uses secondary KMS key grants for model encryption, which means that they’re automatically retired as soon as the operation that Amazon Bedrock performs on behalf of the customer is completed. The Encryption of model customization jobs and artifacts describes in more detail how grants are used.
To completement these IAM policy guardrails, you can add network controls to reduce the scope of the permissions of the process. Because we focus on IAM policies in this post, we won’t go into details here but only mention how the process works.
When you start a model customization job, a model training job is triggered within the model deployment account. The training job takes a base model from its S3 bucket, then connects to the S3 bucket that holds the customization training data to start the customization. This can be done through your VPC, where you specify a VPC configuration such as subnets and security groups, and the training job places an elastic network interface (ENI) into that VPC as specified. A request to the S3 bucket to read the training data now adheres to whatever routing rules are present in the VPC for that ENI. The VPC routing and security group attached to the ENI can be used to limit networking access to the model customization job.
Amazon Bedrock Agents
Amazon Bedrock Agents offers the capability to build and configure autonomous agents for applications. You can find more information about Amazon Bedrock Agents in Automate tasks in your application using AI agents.
Using an Amazon Bedrock agent also provides certain security properties that are applied to an inference task. For example, at the time of writing, there is no IAM condition key for the bedrock:InvokeModel API to require an Amazon Bedrock guardrail being attached to that same call. However, you can require that inferences are invoked through a call to an agent that has specific Amazon Bedrock guardrails configured.
Let’s say that you want to create a role that explicitly is only allowed to invoke Amazon Bedrock models through a specific Amazon Bedrock agent. The following IAM principal permissions policy example implies that the Amazon Bedrock agent specified has approved Amazon Bedrock guardrails configured. Again replace <region>, <account-id>, <bedrock-agent-id>, and <bedrock-agent-alias-id> with the values of your Amazon Bedrock agent.
Provided that the Amazon Bedrock agent is configured by a systems administrator or operator with an approved Amazon Bedrock guardrail, the principal with the preceding policy attached to it will be able to invoke it with a prompt, and won’t directly invoke an Amazon Bedrock model. This strategy for making sure that Amazon Bedrock guardrails are applied to all Amazon Bedrock invocations is currently not possible with the bedrock:InvokeModel and bedrock:InvokeModelWithResponseStream APIs, because they don’t have a condition key to match an Amazon Bedrock guardrail to. In addition, denying bedrock:InvokeModel and bedrock:InvokeModelWithResponseStream also denies the Converse APIs and StartAsyncInvoke APIs, so there’s no need to add these separately to the Deny statement.
Because this strategy verifies the use of specific Amazon Bedrock guardrails, you can also use it for the enforcement of specific prompts, IAM service roles, knowledge bases, prompt and completion content restrictions, KMS keys, and FMs in inference invocations. For this approach to be effective, you need to also limit the principals that can create and update Amazon Bedrock agent configurations. Again, this can be restricted using an IAM policy, which is attached to only specific principals.
The following is an example IAM policy statement that gives an attached IAM principal the ability to update the configuration of a specific Amazon Bedrock agent, replacing <region>, <account-id>, and <agent-id> with the Region, account and identifier, and agent identifier that you’re using. If you want this to apply to all agents, replace <agent-id> with an asterisk (*).
Where agents aren’t suitable, users or applications performing inference against the Amazon Bedrock models will need permissions to call the bedrock:InvokeModel, bedrock:InvokeModelWithResponseStream, or bedrock:CreateModelInvocationJob actions. In these cases, it can be desirable to limit the target models, following an allowlisting approach. Also, such permissions would only be attached to roles or applications that need to use them.
The following is an example of such a policy that restricts invocation to Anthropic’s Claude Instant.
You can include detective or reactive controls using Amazon CloudWatch EventBridge rules to detect model invocations that don’t use appropriate Amazon Bedrock guardrails, but that’s outside the scope of this post.
Model testing
Testing is the last step before the solution is deployed. Types of tests include unit tests, integration tests, user acceptance tests, penetration testing, and more. In this phase, you can again verify that the permissions that were assigned are indeed least privilege.
Especially in functional tests where data is involved, it’s important to consider that the data used for testing might be confidential. This is typically true when no synthetic test data is generated for the testing process. Controls to restrict access to the data and logs that are produced and might contain pieces of this data need to be the same as you will apply in a production environment. That you are only testing the solution doesn’t automatically mean that data access controls aren’t needed.
As discussed earlier in this post, controls are activated not only on identities, but also on the network and on resources. All of these should be validated and their effectiveness confirmed in this phase. Tests include but aren’t limited to:
Validate that you can only perform allowed actions in Amazon Bedrock through VPC endpoints, and that actions that don’t use VPC endpoints are blocked.
Validate the effectiveness of the resource policies on VPC endpoints by making sure that they can only be used by authenticated and authorized principals.
When using knowledge bases, validate that only the Amazon Bedrock service principal can access them.
When using Amazon Bedrock guardrails, evaluate their effectiveness. Because of the nature of generative AI applications, the diversity in input and output data can be big. Therefore, make sure to test guardrails with a reasonably large number of prompts.
If model invocation logging is activated, validate that logs are correctly written and protected with IAM permissions and encryption.
Validate that only the required personnel can access these logs, because they might contain sensitive data. Consider automatically sanitizing and forwarding them to a new CloudWatch log group.
Validate that all relevant Amazon Bedrock API calls are being properly logged in AWS CloudTrail, and that you can effectively monitor and alert on any suspicious activity.
Make sure that sensitive information—such as prompts and responses—isn’t being stored in the CloudTrail logs or in any trace output.
The threat modelling that you have potentially created in the design phase can provide valuable inputs that you can use for security-related test cases.
Model operation
In this phase, the solution is finally deployed into production. Operators need Amazon Bedrock control plane permissions to provision and manage Amazon Bedrock resources such as agents, guardrails, prompt libraries, and knowledge bases. They should only get the control plane permissions to provision and manage the Amazon Bedrock features that are being used. These same operators should have access to invoke or configure the Amazon Bedrock service features or their resources (Amazon Bedrock Agents, Amazon Bedrock Guardrails, and prompt libraries) only through an authorized pipeline. This immutable infrastructure approach restricts human users from creating situations or configurations that would otherwise allow unapproved access to the data plane, untracked changes to the control plane, or potentially disruptive updates to your application.
Alternatively, to reduce the assigned permissions to the absolute minimum, automated deployments using pipelines and pipeline roles can be used. This will not only provide versioned infrastructure but also adheres to PoLP by not providing access to human identities.
After deployment, the solution is live and being accessed by real users. At this point, topics such as monitoring, logging, and incident response become relevant. While Amazon Bedrock by default doesn’t store inference or response data, it’s recommended that you activate logging of those elements to constantly verify the accuracy of your generative AI application.
By using this solution, you reduce access to a minimum in the following areas:
Logged prompts and responses
Data available through knowledge bases, RAG, or similar sources
The ability to change the infrastructure
Use multiple, dedicated, least privileged roles for each task. This helps reduce the permissions scope to a minimum. Also, because least privilege enforces using a specific role for a specific task, it reduces the risk of unintended changes by requiring the assumption of a specific role.
By following the AWS Security Reference Architecture, security monitoring data is consolidated in a central security account. This allows a comprehensive, central overview of the security posture of your infrastructure.
Logging sensitive information
An important operational aspect is logging potentially sensitive data that’s sent to or received from the LLM. While Amazon Bedrock doesn’t store prompts or responses, you can use model invocation logging to collect invocation logs, model input data, and model output data for all invocations in your AWS account used in Amazon Bedrock. Model invocation logging isn’t enabled by default. After it’s enabled, prompts, completions, or both for all invocations of all approved models are then logged to the configured log destination. Valid log destinations for prompt and completion logs are Amazon S3 and CloudWatch. When writing logs to these destinations, they can optionally be encrypted using a supplied KMS key.
The contents of these logs might contain sensitive information in the prompt provided by the user or the reply generated by the model. As such, access to these logs should be restricted to personnel and machine processes that require and are authorized to access this classification of data. There are strategies such as using Amazon Macie on the Amazon S3 logs and CloudWatch Logs data protection capabilities to detect, monitor, and redact this sensitive information from logs, but that’s outside the scope of this post.
Even with Amazon Bedrock guardrails in place, the contents of these logs contain the pre-guardrailed user input, and so you must assume that these prompt and completion logs contain sensitive information. In this case, best practice is to encrypt log data with a KMS key, apply a data protection policy to the log group, and define at least three IAM roles:
BasicCompletionLogReviewer: An IAM role whose sole purpose is to access and review the redacted version of these logs.
SensitiveDataCompletionLogReviewer: A restricted IAM role whose sole purpose is to access and review the unredacted version of these logs.
CompletionLogAdmin: A restricted IAM role whose sole purpose is to create, view, and delete data protection policies that can send audit findings to Amazon S3 and CloudWatch destinations.
To allow reading log events in a specific log group, use a policy such as the following and attach it to the BasicCompletionLogReviewer role, replacing <region>, <account-id>, <log-group-name>, and <alias-name> with values that match your CloudWatch log group and the KMS key that encrypts it.
With an active data protection policy in place, the preceding policy won’t allow access to the unredacted version of these logs. To allow access to the unredacted versions to the SensitiveDataCompletionLogReviewer role, you need to add an additional action, replacing <region>, <account-id>, <log-group-name>, and <alias-name> with values that match your CloudWatch log group and the KMS key that encrypts it.
The policy for the CompletionLogAdmin role requires different permissions; the following sample policy allows a user to create, view, and delete data protection policies that can send audit findings to all three types of audit destinations. It doesn’t permit the user to view unmasked data. This policy will look like the following example, replacing <delivery-stream-id>, <bucket-name>, <log-group-name>, and <alias-name> with the values that match your setup. Note that this includes a statement that explicitly denies the attached role access to decrypt the logs with the configured KMS key, aligning with the PoLP:
This approach helps to avoid inadvertent access to or exposure of this sensitive data source and upholds the PoLP by separating duties.
Review IAM permissions on a periodic basis
Managing permissions is an ongoing effort because requirements and functionality change over time. Therefore, we recommend regularly reviewing the assigned permissions and verifying that they aren’t overly permissive. For example, if you have a Lambda function that makes API calls to Amazon Bedrock, and changes are made to that function that require additional permissions (perhaps the use of a new model), then it’s acceptable to update the policy attached to the IAM role that the function uses. It’s not always obvious that permissions for using the earlier model are still needed in the same policy; or permissions might be widened unnecessarily to include all models. When applying the PoLP, it’s important that policies be tested at the time they’re deployed to make sure that they meet the exact application needs and no more, but also that the presumed needs are reviewed periodically.
Using AWS IAM Access Analyzer, you can review and simulate proposed changes to IAM policies to ensure their suitability for a given application or function. You can also use IAM Access Analyzer to review unused permissions over time. This gives system operators an opportunity to inspect and then inform the removal of unused permissions in policies used with Amazon Bedrock applications. Remember that some permissions are dormant and ready for periodic use, such as incident response, recovery and other rare use cases, so your review shouldn’t assume that an unused permission is unnecessary, but an opportunity to review the need for the permission.
Finally, align monitoring of new Amazon Bedrock APIs with your IAM strategy. Especially when using denylisting approaches, it’s important to consider that services will announce new APIs, capabilities, and FMs over time. An example for this was the announcement of the new Converse API. This API provides functionality similar to Invoke, but in a consistent and thus simpler way. Considering such changes is therefore an integral part of your regular policy review processes.
Strong identity and access management is a journey, not a one-time action.
Conclusion
In this post, we have demonstrated some ways that you can apply the principle of least privilege (PoLP) to large language model (LLM)-based applications that use Amazon Bedrock. We have discussed the security considerations of each phase of the development lifecycle and provided examples that you can use as a starting point to implement your own PoLP strategy. It’s important that security doesn’t start late in the process; think about risks and the required actions as early as possible to make sure that your strategy is effective when your application goes live.
Finally, remember that the field of generative AI is moving quickly. We believe that it has the potential to transform virtually every customer experience. From a security perspective, this means that the threat landscape will change and evolve over time. Make sure to constantly adapt to new risks; evaluate and integrate them into your PoLP strategy.
Your AWS account team and specialists are happy to assist you on this journey.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Establishing and maintaining an effective security and governance posture has never been more important for enterprises. This post explains how you, as a security administrator, can use Amazon Web Services (AWS) to enforce resource configurations in a manner that is designed to be secure, scalable, and primarily focused on feature gating.
In this context, feature gating means that newly supported AWS features and configurations can’t be used unless you explicitly approve them. With feature gating, you maintain control over your AWS environment when new services and capabilities are introduced.
This blog post demonstrates a unique approach to giving users, such as DevOps teams, controlled flexibility within safe boundaries by allowing resource provisioning that uses only approved configurations. This approach also accommodates configurations that will be supported in future versions of the resource, keeping them restricted until explicitly approved, as shown in Figure 1.
Figure 1: Restrict resource provisioning to approved configurations only
Apply your resource configuration enforcement
As shown in Figure 2, our solution for resource configuration enforcement (RCFGE) uses AWS CloudFormation Hooks. By using Hooks, you can run custom logic during the provisioning of resources. These are proactive controls because you inspect and enforce resource configurations before the resource is created, updated, or deleted.
Your Hook will only be effective if CloudFormation supports the AWS resources that you are using and if you implement a service control policy (SCP) that helps prevent users from provisioning resources outside of CloudFormation.
Figure 2: How CloudFormation Hooks work
The flow shown in Figure 2 consists of the following five steps:
DevSecOps registers and configures a CloudFormation Hook in the account.
DevOps specifies a CloudFormation template that defines the required resources and configurations.
CloudFormation creates a new stack resource, starting the provisioning process based on the template.
The Hook is triggered before provisioning for each resource that’s defined in the template, and runs custom validation logic.
If the validation checks pass, CloudFormation proceeds with provisioning; if not, the process is terminated.
Make your solution scalable
To achieve scalable operations, you should implement a reusable and generic Hook that targets all supported CloudFormation resource types. This Hook enforces resource configuration by loading resource specification files from an external object storage, such as an Amazon Simple Storage Service (Amazon S3) bucket.
These specification files define validation rules in a declarative language. Using this approach, you can add and remove resource configuration validation rules by editing the declarative files. When you externalize custom logic as decoupled validation rules from the Hook, DevSecOps personnel can manage these rules at scale without affecting your infrastructure.
Figure 3: Externalize custom logic as validation rule files in an S3 bucket
Figure 3 shows how the solution has been revised to support this approach. Steps 1–3 are the same as in the flow shown in Figure 2:
DevSecOps registers and configures a CloudFormation Hook in the account.
DevOps specifies a CloudFormation template that defines the required resources and configurations.
CloudFormation creates a new stack resource, starting the provisioning process based on the template.
The Hook is triggered before provisioning for each resource that’s defined in the template.
The Hook loads the relevant resource specification file from the S3 bucket and executes the validation rules against the current resource in the CloudFormation template.
If the validation checks pass, CloudFormation proceeds with provisioning; if not, the process is terminated.
You need to configure the Hook schema and the Hook configuration schema to evaluate the configurations of all supported resources across your AWS accounts before changes are provisioned. This setup should cover create, update, and delete operations so that the Hook can help prevent non-approved configurations across stacks.
By using AWS CloudFormation Guard, you can externalize validation rules from the Hook, as described in Extend your pre-commit hooks with AWS CloudFormation Guard. Guard is an open source, general purpose, policy-as-code (PaC) evaluation tool that validates CloudFormation templates against custom rules to help you stay aligned with your organizational policies. For example, the CT.S3.PR.1 rule specification demonstrates a Guard rule that requires an S3 bucket to have its settings configured to block public access. These validation rules apply to currently supported AWS resource configurations and features, but they don’t restrict potential future properties.
Boost your solution with feature gating
Your risk model might lead you to look for mechanisms that further restrict the AWS resource configurations that you allow in your environments. As you will see, the proposed solution restricts authorized workforce users so that they can use new configurations only if you enable them. The proposed approach uses feature gating because it continues to enforce your configurations even when AWS adds new options for your resources.
Guard aims to validate required constraints; but to meet the feature gating objective, you should implement validation rules that check whether resource configurations fulfill structural constraints described by the restricted version of CloudFormation resource schemas. These schemas help you confine the possible resource configurations that can be provisioned in your environment no matter what new configurations AWS introduces.
Figure 4: Enforce resource configuration with restricted resource schema templates
Figure 4 shows an updated version of the same flow where validation rules are implemented by using restricted resource schema templates, which are stored in an S3 bucket. These templates are based on the original CloudFormation resource schemas, representing a snapshot of these schemas at a specific point in time. Steps 1–4 are the same as in the flow shown in Figure 3:
DevSecOps registers and configures a CloudFormation Hook in the account.
DevOps specifies a CloudFormation template that defines the required resources and configurations.
CloudFormation creates a new stack resource, starting the provisioning process based on the template.
The Hook is triggered before provisioning for each resource that’s defined in the template.
The Hook loads the relevant restricted resource schema template file from the S3 bucket and uses it to execute schema validation against the current resource in the CloudFormation template.
If the validation checks pass, CloudFormation proceeds with provisioning; if not, the process is terminated.
A restricted resource schema template is a subset of its corresponding original CloudFormation resource schema. It includes additional constraints that limit certain properties to specific values and patterns or exclude certain properties entirely. Furthermore, these templates contain placeholders that you fill in with runtime values, such as the account ID, which your Hook provides as part of the Hook context.
As shown in Figure 5, the flow within the RCFGE CloudFormation Hook involves the following steps:
The CloudFormation Hook is invoked with the Hook context and the resource’s configuration JSON object.
The Hook loads the restricted resource schema template from the S3 bucket and substitutes placeholders with the Hook context runtime values, producing a valid JSON schema.
The Hook validates the stack’s resource configuration JSON object against the schema. If it returns OperationStatus.SUCCESS, then CloudFormation proceeds with the provisioning process. If it returns OperationStatus.FAILED, then CloudFormation terminates the provisioning process.
If a restricted resource schema template for a CloudFormation resource type isn’t found in the S3 bucket, the schema validation step fails by default.
Sample excerpt of a restricted schema template for an S3 bucket resource
The following is an excerpt from a restricted schema template for an S3 bucket. At runtime, your Hook processes this template, substituting the placeholders with relevant values from the Hook context. In this example, the Hook replaces the <accountID> placeholder in the topic’s pattern with the actual account ID. The resulting JSON schema disallows additional properties beyond those defined by the schema and restricts the Amazon Simple Notification Service (Amazon SNS) topics that can be used for event notifications.
Note: In the code samples that follow, we’ve omitted some code for brevity—we’ve indicated these omissions with three periods: ...
CloudFormation template for an S3 bucket that adheres to the restricted schema
Let’s assume that your account ID is 111122223333. The account ID is propagated to the Hook through the Hook context.
The following is an excerpt from a CloudFormation template that aligns with the restricted schema for an S3 bucket instantiated from the template shown previously. As a result, your Hook allows the corresponding CloudFormation stack to proceed.
CloudFormation template for an S3 bucket that diverges from the restricted schema (example 1)
The following is an excerpt from a CloudFormation template that doesn’t align with the restricted schema for an S3 bucket instantiated from the template shown previously because it attempts to configure the Amazon SNS topic for the notification configuration, which uses an Amazon Resource Name (ARN) of another account. As a result, your Hook causes the corresponding CloudFormation stack to fail.
CloudFormation template for an S3 bucket that diverges from the restricted schema (example 2)
The following is an excerpt from a CloudFormation template that doesn’t align with the restricted schema for an S3 bucket instantiated from the template shown previously. This time, it violates your feature gating objective by attempting to use a new, imaginary feature of an S3 bucket that isn’t approved for use by your restricted schema for an S3 bucket. As a result, your Hook causes the corresponding CloudFormation stack to fail.
If a security control itself isn’t protected adequately, it becomes a weak link in the security chain. For example, a surveillance camera (a physical security control) that isn’t securely mounted can be removed, rendering it useless. This principle also applies to your RCFGE solution.
Next, we will show you how to isolate management activities to a dedicated account and use SCPs as preventative controls.
Isolate RCFGE management in a dedicated account
Organizing your AWS environment by using multiple accounts is a best practice because it enhances security, simplifies management, and allows for better resource isolation and cost tracking. Isolating the operation and management of your RCFGE solution in its own dedicated account is essential for securing the solution’s resources.
With AWS CloudFormation StackSets, you can deploy and manage RCFGE stacks across multiple accounts and AWS Regions from a single central administrator account. This provides consistent and scalable infrastructure while maintaining centralized governance. With this functionality, you can deploy the RCFGE resources to existing accounts and automatically include new accounts as you add them to your organization, simplifying RCFGE management and providing uniformity across your environments. For more information, see Deploy CloudFormation Hooks to an Organization with service-managed StackSets.
Figure 6 shows how to extend that idea so that you can operate the RCFGE solution at scale while maintaining isolation and the separation of duties. The solution operates across three key account types:
Management account –use this account to create your organization and designate the CloudFormation StackSets delegated administrator account.
Delegated administrator account – this account serves as the centralized management point for the RCFGE solution. It contains a continuous integration and continuous delivery (CI/CD) pipeline that provisions RCFGE resources across the organization by using CloudFormation StackSets with service managed permissions. The account hosts a centralized S3 bucket that stores the RCFGE restricted resource schema templates. The security engineering team uses this account to submit Hook code and restricted resource schema template changes, which trigger the CI/CD pipeline.
Member accounts – each member account contains an RCFGE StackSet instance and an AWS Identity and Access Management (IAM) role for provisioning RCFGE resources. It also includes a CloudFormation Hook and an IAM role that allows the Hook to access the centralized S3 bucket with RCFGE restricted resource schema templates.
Figure 6: Securely operate the RCFGE solution
Let’s explore how the RCFGE solution architecture enforces resource configuration step by step, as shown in Figure 7.
Figure 7: CloudFormation stack deployment flow with RCFGE validation and enforcement
DevOps initiates the deployment by specifying a CloudFormation template that defines the resources and configurations needed.
CloudFormation creates a new stack resource, initiating the resource provisioning process based on the provided template.
The RCFGE CloudFormation Hook is triggered for each resource defined in the CloudFormation template.
The Hook loads the corresponding restricted resource schema template from the S3 bucket.
The Hook validates a resource configuration:
The Hook processes the restricted resource schema template to create a JSON schema.
It uses this JSON schema to validate the current resource in the CloudFormation template.
If the resource is invalid according to the schema, the provisioning process is terminated.
If the current resource passes validation, CloudFormation proceeds with the resource provisioning process by creating and configuring the resources as specified in the template.
Use SCPs as preventive controls for your organization to help protect RCFGE
The following SCP excerpt accomplishes three objectives:
Implements a statement (see AllowedListActions) to explicitly specify the access that is allowed while other access is implicitly blocked.
Implements control objectives to help prevent changes to resources set up by the RCFGE solution (see ProtectRCFGEResources and ProtectStackSetExecutionRole).
Makes sure that AWS resource provisioning does not occur outside of CloudFormation (see ProvisionResourcesViaCloudFormationOnly).
In this SCP excerpt, the ProvisionResourcesViaCloudFormationOnly statement restricts CloudFormation stacks to being managed only through forward access sessions (FAS) in AWS IAM.
The ProvisionResourcesViaCloudFormationOnly statement explicitly prohibits direct create, update, and delete actions for all supported resources used in your environment. If needed, split this statement into multiple parts so you don’t exceed SCP size limits, while providing comprehensive coverage of your resources to make sure that they are provisioned and managed only through CloudFormation.
The ProtectStackSetExecutionRole statement in this example assumes that CloudFormation trusted access is activated with AWS Organizations, which is required by StackSets to deploy across accounts and Regions by using service managed permissions.
To allow the Hook to retrieve the necessary restricted resource schema templates, member accounts must be able to access the S3 bucket that contains the RCFGE templates. The following code sample shows the bucket policy for the S3 bucket that contains the RCFGE templates.
As shown in the following code sample, the RCFGEHookExecutionRole IAM role in member accounts has a policy that grants read-only access to the RCFGE templates that are stored in an S3 bucket in the RCFGE delegated administrator account, where 555555555555 represents the account ID.
In the following code sample, the RCFGEHookExecutionRole IAM role in member accounts has a trust policy that allows it to be assumed only by the relevant CloudFormation service principals, where 444455556666 represents the account ID of the member account.
Define baseline configuration for RCFGE and continuous monitoring with AWS Config
Defense in depth is an effective strategy because if one line of defense fails, additional layers are in place to help stop threats at subsequent points. With AWS Config, you can capture the configuration of RCFGE resources over time. You can set up AWS Config custom rules to automatically assess the compliance of your RCFGE resources against predefined policies. For example, you can use an AWS Config custom rule to make sure that the RCFGE Hook hasn’t been altered or removed.
Conclusion
In this post, you learned how to use CloudFormation Hooks to create a resource configuration enforcement (RCFGE) solution on AWS that is designed to be secure and scalable and that supports feature gating. Using this approach, you, as a security administrator, can maintain strict control over resource configurations and feature adoption across your AWS environments. The solution provides a balanced approach to governance, so that DevOps teams have the flexibility to work within approved boundaries while making sure that new AWS features are only accessible after explicit approval.
If you have feedback about this post, submit comments in the Comments section. For questions, start a new thread on the CloudFormation re:Post or contact AWS Support.
Amazon Web Services (AWS) recently released AWS IAM Identity Centertrusted identity propagation to create identity-enhanced IAM role sessions when requesting access to AWS services as well as to trusted token issuers. These two features can help customers build custom applications on top of AWS, which requires fine-grained access to data analytics-focused AWS services such as Amazon Q Business, Amazon Athena, and AWS Lake Formation, and Amazon S3 Access Grants. You can use AWS services compatible with trusted identity propagation to grant access to users and groups belonging to IAM Identity Center instead of solely relying on AWS Identity and Access Management (IAM) role permissions. With a trusted token issuer, you can propagate identities that you have authenticated in your custom application to the underlying AWS services. In the case of an Amazon Q Business application, you can create a different web experience or integrate an Amazon Q Business application as an assistant into an existing web application to help your workforce.
These two features rely on the OAuth 2.0 protocol to exchange user information. For the identity to be consumable by AWS services, your custom application’s identity provider needs to be able to issue OAuth 2.0 tokens for your users.
This blog post from November 2023 covers how to interconnect with an OAuth 2.0 compatible identity provider such as Microsoft Entra ID, Okta, or PingFederate.
In this post, I show you how to use an Amazon Cognito user pool as a trusted token issuer for IAM Identity Center. You will also learn how to use IAM Identity Center as a federated identity provider for a Cognito user pool to provide a seamless authentication flow for your IAM Identity Center custom applications. Note that this content doesn’t cover building a custom application for Amazon Q Business. If needed, you can find more details in Build a custom UI for Amazon Q Business.
IAM Identity Center concepts
IAM Identity Center is the recommended service for managing your workforce’s access to AWS applications. It supports multiple identity sources, such as an internal directory, external Active Directory, or a SAML-compliant identity provider (IdP) with optional SCIM integration.
With trusted identity propagation, a user can sign in to an application, and that application can pass the user’s identity context when creating an identity-enhanced AWS session to access data in AWS services. Because access is now tied to the user’s identity in IAM Identity Center, AWS services can rely on both the IAM role permissions to authorize access as well as the user’s granted scopes and group memberships.
Trusted token issuers are OAuth 2.0 authorization servers that create signed tokens and enable you to use trusted identity propagation with applications that authenticate outside of AWS. With trusted token issuers, you can authorize these applications to make requests on behalf of their users to access AWS managed applications. The trusted token issuers feature is completely independent from the authentication feature of IAM Identity Center and doesn’t need to be the same identity provider as is used for authenticating into IAM Identity Center.
When performing a token exchange, the token must contain an attribute that maps to an existing user in IAM Identity Center, such as an email address or external ID. A token can be exchanged only once.
On the other side, an Amazon Cognito user pool is a user directory and an OAuth 2.0 compliant identity provider (IdP). From the perspective of your application, a Cognito user pool is an OpenID Connect (OIDC) IdP. Your application users can either sign in directly through a user pool, or they can federate through a third-party IdP. When you federate Cognito to a SAML IdP, or OIDC IdPs, your user pool acts as a bridge between multiple identity providers and your application.
Overview of solution
The solution architecture includes the following elements and steps and is depicted in Figure 1.
The custom application: The custom application provides access to the Amazon Q Business application through APIs. Users are authenticated using Amazon Cognito as an OAuth 2.0 IdP.
Amazon Q Business: The Amazon Q Business application requires identity-enhanced AWS credentials issued by AWS Security Token Service (AWS STS) to authorize requests from the custom application.
AWS STS: STS issues identity-enhanced AWS credentials to the custom application through the setContext and AssumeRole API calls. SetContext requires the user’s identity context to be passed from a JSON web token (JWT) issued by IAM Identity Center.
IAM Identity Center: To issue a JWT, IAM Identity Center requires the custom application to perform a token exchange operation from a trusted IAM role and a trusted token issuer (Cognito).
Amazon Cognito user pool: The user pool authenticates users into the custom application. The user pool uses SAML federation to delegate authentication to Identity Center. Users are automatically created in the user pool when the federated authentication is successful. The user pool returns a JWT to the custom application.
SAML-based customer managed application (when IAM Identity Center is acting as a SAML identity provider): By using the SAML customer managed application in IAM Identity Center, you can delegate the authentication from Cognito to IAM Identity Center. One benefit of using IAM Identity Center is to help guarantee that the user exists in IAM Identity Center before authenticating to Cognito, as long as IAM Identity Center is the only way to authenticate to the client application. User existence is a requirement to perform the token exchange operation.
Figure 1: Solution architecture
Walkthrough
The focus of this post is steps 3–6 of the architecture, which follow a three-step approach.
Creation and initial configuration of the Amazon Cognito user pool and domain
Configuration of the OAuth integration for trusted identity propagation
Configuration of the SAML federation trust between IAM Identity Center and Cognito
Prerequisites
For this walkthrough, you need the following prerequisites:
Step 1: Create the Cognito user pool, the user pool domain and the user pool client
The following bash script sets up the Amazon Cognito user pool, user pool domain, and user pool client and outputs the issuer URL and audience that you need to set up IAM Identity Center.
Note: The Cognito user pool domain prefix must be unique across all AWS accounts for a given AWS Region. Replace <demo-tti> with a unique prefix for your user pool domain.
#!/bin/bash
export AWS_PAGER="" # Disable sending response to less
export USER_POOL_NAME=BlogTrustedTokenIssuer
export COGNITO_DOMAIN_PREFIX=<demo-tti> # Must be unique
# Create the user pool
USER_POOL_ID=$(aws cognito-idp create-user-pool \
  --pool-name ${USER_POOL_NAME} \
  --alias-attributes email \
  --schema Name=email,Required=true,Mutable=true,AttributeDataType=String \
  --query "UserPool.Id" \
  --admin-create-user-config AllowAdminCreateUserOnly=True \
  --output text)
# Create the user pool domain
aws cognito-idp create-user-pool-domain \
  --domain ${COGNITO_DOMAIN_PREFIX} \
  --user-pool-id ${USER_POOL_ID}
# Create the user pool client
AUDIENCE=$(aws cognito-idp create-user-pool-client \
  --user-pool-id ${USER_POOL_ID} \
  --client-name TTI \
  --explicit-auth-flows ALLOW_REFRESH_TOKEN_AUTH ALLOW_USER_SRP_AUTH \
  --allowed-o-auth-flows-user-pool-client \
  --allowed-o-auth-scopes openid email profile \
  --allowed-o-auth-flows code \
  --callback-urls "http://localhost:8080" \
  --query "UserPoolClient.ClientId" \
  --output text )
ISSUER_URL="https://cognito-idp.${AWS_REGION}.amazonaws.com/${USER_POOL_ID}"
Step 2: Create the OAuth integration for trusted identity propagation
To create the OAuth integration, you need to set up a trusted token issuer and configure the OAuth customer managed application.
Configure a trusted token issuer
Start by configuring IAM Identity Center to trust tokens issued by the Amazon Cognito user pool.
Create the OAuth customer managed application, which will allow your AWS account to exchange tokens issued for the Cognito user pool client.
# Create the OAuth customer managed application
OAUTH_APPLICATION_ARN=$(aws sso-admin create-application \
    --instance-arn $INSTANCE_ARN \
    --application-provider-arn "arn:aws:sso::aws:applicationProvider/custom" \
    --name DemoApplication \
    --output text \
    --query "ApplicationArn")

# Disable using explicit assignment for user access to this application
aws sso-admin put-application-assignment-configuration \
    --application-arn $OAUTH_APPLICATION_ARN \
    --no-assignment-required
# Allow token exchange process for tokens issuer by the trusted token issuer
cat << EOF > /tmp/grant.json
{
  "JwtBearer": {
    "AuthorizedTokenIssuers": [
      {
        "TrustedTokenIssuerArn": "$TRUSTED_TOKEN_ISSUER_ARN",
        "AuthorizedAudiences": ["$AUDIENCE"]
      }
    ]
  }
}
EOF
aws sso-admin put-application-grant \
    --application-arn $OAUTH_APPLICATION_ARN \
    --grant-type "urn:ietf:params:oauth:grant-type:jwt-bearer" \
    --grant file:///tmp/grant.json
# Allow use of this application for Q Business applications
for scope in qbusiness:messages:access qbusiness:messages:read_write qbusiness:conversations:access qbusiness:conversations:read_write qbusiness:qapps:access; do
    aws sso-admin put-application-access-scope \
        --application-arn $OAUTH_APPLICATION_ARN \
        --scope $scope
done
# Allow this AWS Account Id to invoke the API to exchange token (CreateTokenWithIAM)
AWS_ACCOUNTID=$(aws sts get-caller-identity --output text --query "Account")
cat << EOF > /tmp/authentication-method.json
{
  "Iam": {
    "ActorPolicy": {
      "Version": "2012-10-17",
      "Statement": [
        {
          "Effect": "Allow",
          "Principal": {
            "AWS": "${AWS_ACCOUNTID}"
          },
          "Action": "sso-oauth:CreateTokenWithIAM",
          "Resource": "$OAUTH_APPLICATION_ARN",
        }
      ]
    }
  }
}
EOF
aws sso-admin put-application-authentication-method \
  --application-arn $OAUTH_APPLICATION_ARN \
  --authentication-method file:///tmp/authentication-method.json \
  --authentication-method-type IAM
Step 3: Create the SAML federation trust between IAM Identity Center and Cognito
The SAML integration between IAM Identity Center and Amazon Cognito is useful when your source of identity is IAM Identity Center. In this scenario, SAML integration helps ensure that users will authenticate with IAM Identity Center credentials before being authenticated to your Cognito user pool. When using federated identities, the Cognito user pool will automatically create user profiles, so you don’t need to maintain the user directory separately.
Configure IAM Identity Center
Sign in to the AWS Management Console and navigate to IAM Identity Center.
Choose Applications from the navigation pane.
Choose Add application.
Select I have an application I want to set up, select SAML 2.0, and then choose Next.
For Display name, enter DemoSAMLApplication.
Copy the IAM Identity Center SAML metadata file URL for later use.
For Application properties, leave both fields blank.
For Application ACS URL, enter https://<CognitoUserPoolDomain>.auth.<AWS_REGION>.amazoncognito.com/saml2/idpresonse.
Replace <CognitoUserPoolDomain> with the domain you chose in Step 1 and <AWS_REGION> with the Region in which you created the Cognito user pool.
For Application SAML audience, enter urn:amazon:cognito:sp:<CognitoUserPoolId>.
Replace <CognitoUserPoolId> with the ID of the Cognito user pool you created in Step 1.
Choose Submit.
Configure mapping attributes
Choose Actions and select Edit attribute mappings.
Enter ${user:email} for the field Maps to this string value or user attribute in IAM Identity Center.
Select Persistent for Format.
Choose Save changes.
Configure Cognito user pool
Navigate to the Amazon Cognito console and choose User pools from the navigation pane.
Select the user pool created in Step 1.
Choose the Sign-in experience tab.
Under Federated identity provider sign-in, choose Add identity provider.
Select SAML.
Under Provider name, enter IAMIdentityCenter.
Under Metadata document source, select Enter metadata document endpoint URL and paste the URL copied from step 6 of Configure IAM Identity Center
Under SAML attribute, enter Subject.
Choose Add Identity Provider.
Configure app integration to use IAM Identity Center
Choose the App integration tab.
Under App clients and analytics, choose TTI.
Under Hosted UI, choose Edit.
For Identity providers, select IAMIdentityCenter.
Choose Save changes.
Architecture diagram
Figure 2 shows the authentication flow from the user connecting to the web application up to the chat interaction with Amazon Q Business APIs.
Note: The AWS resources can be in the same Region, but it’s not required for Amazon Cognito and IAM Identity Center.
The application redirects the user to Amazon Cognito for authentication.
Cognito redirects the user to IAM Identity Center for authentication.
Cognito parses the SAML assertion from IAM Identity Center.
Cognito returns a JWT to the application.
The application exchanges the token with IAM Identity Center.
The application assumes an IAM role and sets the context using the IAM Identity Center token.
The application invokes the Amazon Q Business APIs with the context-aware STS session.
Figure 2: Authentication flow
Clean up
To avoid future charges to your AWS account, delete the resources you created in this walkthrough. The resources include:
The Amazon Cognito user pool (deleting this will also delete sub resources such as the user pool client)
The SAML application in IAM Identity Center
The OAuth application in IAM Identity Center
The trusted token issuer configuration in IAM Identity Center
Conclusion
In this post, we demonstrated how to implement trusted identity propagation for applications that are protected by Amazon Cognito. We also showed you how to authenticate Cognito users with IAM Identity Center to help ensure that users are authenticating using the correct mechanisms and policies and to reduce the operational burden of managing the Cognito directory by automatically provisioning users as they sign in.
Using Amazon Cognito as a trusted token issuer is useful when your application is already secured with a user pool, and you want to implement data functionalities such as Amazon Q Business chat capabilities or secure access to S3 buckets using S3 Access Grants.
If your users are authenticating with different identity providers, the solution in this post can reduce the work needed for identity integration by enabling you to add multiple identity providers to a single user pool. By using this solution, you will need to configure the trusted token issuer in IAM Identity Center only for Amazon Cognito and not for every token provider.
This walkthrough doesn’t include a demo web application because I wanted to dive into the integration of IAM Identity Center and Amazon Cognito. I recommend reading Build a custom UI for Amazon Q Business, which shows you how to implement a custom user interface for an Amazon Q Business application using Amazon Cognito for user authentication.
Because trusted identity propagation is becoming more prevalent within AWS services, I recommend the following blog posts to learn more about using it with various services.
Externalized authorization for custom applications is a security approach where access control decisions are managed outside of the application logic. Instead of embedding authorization rules within the application’s code, these rules are defined as policies, which are evaluated by a separate system to make an authorization decision. This separation enhances an application’s security posture by aligning with Zero Trust principles of continual real-time authorization, simplifies the management of security policies, and enables consistent policy enforcement across multiple applications. Amazon Verified Permissions is a scalable permissions management and fine-grained authorization service that you can use to externalize application authorization.
Two common access control models that you might consider when implementing your authorization system are role-based access control (RBAC) and attribute-based access control (ABAC). RBAC grants permissions to users based on their assigned roles within an organization, simplifying the management of access by grouping permissions into roles that correspond to job functions. ABAC grants permissions based on a set of attributes associated with users, resources, and the context, allowing for more fine-grained and dynamic authorization decisions. However, as systems become more complex and have more interconnected data—especially in environments like social networks, collaborative environments, and multi-tenant applications—the limitations of RBAC and ABAC become apparent. These models often fail to effectively capture the relationships between entities. Relationship-based access control (ReBAC) offers a more nuanced approach by using the relationships between users and resources to make decisions about permitted actions, thus addressing scenarios more efficiently than other models.
In this blog post, we show you how to implement ReBAC using Verified Permissions and Amazon Neptune, a managed, serverless graph database on AWS.
What is relationship-based access control?
The core principle of ReBAC is that authorization decisions are based on the relationships between the principal requesting access and the resource being accessed. These relationships can be of several types—ownership, collaboration, or membership relationships—that form hierarchical structures. Examples of ReBAC can be found in multiple domains, including social media sites, project management tools, and content management systems. For example, in a social media application, ReBAC can be used to control who can view, comment, or share a post based on the relationships between the poster, their connections, and the content itself.
Conceptually, roles are types of relationships, and relationships are subsets of attributes.
Benefits of ReBAC
In some types of applications, relationships change dynamically. For example, in a collaborative or social media application, relationships such as contributor or co-owner are continually being established between individual users and resources. Compared to traditional access control models, ReBAC offers the following benefits in these use cases.
Fine-grained access control – ReBAC grants access at the level of an individual resource based on a user’s relationship with that resource. For example, a user can update individual photo albums with which they have a contributor relationship.
Scalability and adaptability – Relationships can change dynamically. Access permissions are updated automatically when a relationship changes. For example, when the contributor relationship is removed, the user no longer has access.
Support for hierarchies – ReBAC can handle hierarchical relationships. For example, the contributor relationship can be inherited down through an album hierarchy, permitting the user to update photo albums that are members of the album with which they have the relationship.
Common relationship models in ReBAC
Here are some common relationship models, also shown in Figure 1, for consideration when building the application and its authorization system:
Resource ownership – Permissions to access or manipulate a resource are granted based on whether a user owns that resource. For example, you can delete a GitHub repository if you are the owner of the repository.
Resource hierarchies – Permissions to access or manipulate a resource are granted based on the permissions that a principal has for the parent resource. For example, a GitHub repository contributor can close issues that belong to that repository.
User hierarchies – These are similar to AWS Identity and Access Management (IAM) user groups. Principals that belong to a group will have the permissions granted to that group.
Figure 1: Common relationship models in ReBAC
In a relationship model, direct relationships represent clear, explicit links between users and resources, such as an employee owns their expense reports or a file is a member of a folder. These connections are straightforward and simply definable.
However, relationship models often extend beyond these direct links to include hierarchical structures. These create indirect relationships that are more complex in nature. For example, team managers might have access to all expense reports filed by their subordinates, even though they don’t directly own these reports. Similarly, folder owners might have access to all files within their subfolders, regardless of who created those files.
These indirect relationships are derived from a series of direct relationships. They form a relationship chain that, while not explicitly defined, is implied by the hierarchical structure. Because of their complexity and potential for far-reaching implications, these indirect relationships require careful consideration when designing an authorization system.
In this blog post, we focus on the implementation of the relationship models that use resource ownership and resource hierarchies, and relationship hierarchies in these models.
Example scenario
Consider a video application that allows users to manage and share videos of their pets. Alice and Bob are individual users within the environment and so they only have access permissions to their own directory or videos. Because Alice and Bob directly own their resources, they have direct OWNER relationships to these resources, represented as solid lines in Figure 2. aliceCatVideo.mp4 is a video resource stored in the aliceVideoDirectory directory. There is a MemberOf relationship between these resources.
Figure 2: Alice has direct relationship to resources that she has direct ownership
Charlie has direct OWNER relationship to the root directory petVideosDirectory. Because aliceVideoDirectory is a subdirectory of petVideosDirectory, Charlie inherits an OWNER relationship to aliceVideoDirectory and the video resource aliceCatVideo.mp4 inside. This indirect OWNER relationship is inherited through the MemberOf relationship between resources and is represented as dotted lines in Figure 3.
Figure 3: Charlie has indirect relationship to resources that inherited from the MemberOf relationship
When implementing access control for this scenario, both RBAC and ABAC offer distinct approaches. In RBAC, you might define roles such as OWNER and VIEWER, and grant Charlie full access to each resource through the OWNER role. While initially straightforward, this method can become inflexible as the application grows, potentially leading to role proliferation. For example, you might want to have separate roles to manage different resources (such as photos or videos) for each type of pet (such as cats or dogs). In ABAC, you might assign attributes such as OWNER and VIEWER and grant each user permissions to resources with specific attributes. This approach offers more flexibility, but fine-grained control can be more complex to set up and manage. As the application’s hierarchy becomes more intricate, both models face challenges in maintaining scalability while maintaining proper access control.
ReBAC addresses these limitations by implementing an access control model that uses direct and indirect relationships between principals and resources. In the example scenario, when Charlie requests access to the video resource aliceCatVideo.mp4, the application traverses the relationship graph in Neptune to retrieve the inherited OWNER relationship through the MemberOf relationship and make the authorization decision.
Overview of a ReBAC application
In this solution, relationship data is stored in Neptune. Prior to requesting an authorization decision from Verified Permissions, the application runs a Neptune query that traverses the relationship graph to retrieve the set of principals that have a specific relationship with the resource. The application then constructs an authorization request for Verified Permissions, using the results of this query to populate the entity data in the request.
In the Cedar schema, the resource has an attribute—named for the relationship—that contains the set of principals that have that relationship with the resource. In our sample application, entities of type Video have an attribute called OWNER, which contains the set of users that have an owner relationship, directly or indirectly, with a video. Each potential relationship is represented by a distinct resource attribute and requires a dedicated query to fetch the set of principals that have that relationship.
See the GitHub repository for the step-by-step walkthrough. In this post, we focus on the key concepts of the solution.
Architecture
Figure 4: Solution architecture
The solution architecture, as shown in Figure 4, includes the following:
The user authenticates with Amazon Cognito and obtains an access token and an ID token.
The user accesses the application through Amazon API Gateway with the provided token.
An application AWS Lambda function traverses the relationship graph in Neptune and returns the set of principals that have a specific relationship with the resource.
The application Lambda function constructs the requests by putting relationship data in the entities field and passes the requests to Verified Permissions. Verified Permissions acts as the policy decision point (PDP) and evaluates the Cedar policies to arrive at an authorization decision.
The application Lambda function acts as the policy enforcement point (PEP) to enforce the authorization decision returned by Verified Permissions by allowing or denying access to the API.
Data modelling and queries in Neptune
Relationships between entities are created and stored in Neptune as a property graph. A property graph is a set of vertices and edges with respective properties (key-value pairs). The vertices represent entities such as User, Directory, and Video in our example, and the edges represent directional relationships between vertices. Each edge has a label that denotes the type of relationship.
Neptune supports multiple graph query languages, including Gremlin, openCypher, and SPARQL, to access a graph. In this solution, we use Gremlin as the graph query language. For more information about Gremlin, see the documentation from Apache TinkerPop. You can use Neptune graph notebooks to work with a Neptune graph.
You can visualize the relationship graph (Figure 5) using the following query. We use elementMap() to include attributes to represent a vertex or an edge.
# Visualizing the relationship graph and extracting the attributes of each vertex and edge
%%gremlin -p v,oute,inv
g.V().outE().inV().path().by(elementMap('name','directoryId','videoId','ownerName','ownerId','userId','isPublic').order().by(keys))
Figure 5: Relationship graph in Neptune
The following code snippet shows how to add a vertex for entity and an edge for relationship in a relationship graph. Static attributes such as ownerId, ownerName, and isPublic are defined as properties of a vertex. In our example, we will define two relationships—MEMBEROF and OWNER—to denote the direct relationships between resources-to-resources and resources-to-users respectively.
It’s a best practice to assign universally unique identifiers (UUIDs) for all principal and resource identifiers. Another best practice is to not include personally identifying, confidential, or sensitive information as part of the unique identifier for your principals or resources.
To traverse the relationship graph to obtain the owner vertex of a resource vertex, you can use the following query. This query returns the vertex that has a direct OWNER relationship to the resource vertex aliceCatVideo.mp4.
# Retrieve the direct owner of a specific video
g.V().hasLabel('video').has('name', 'aliceCatVideo.mp4').in('OWNER').values(‘name’)
You can use the following query to discover inherited OWNER relationships through MemberOf relationships between resources. The query traverses the relationship graph starting from a video vertex and return the OWNER vertex of each resource vertex along the path to the root directory petVideosDirectory. It outputs the set of owners after deduplication. This query discovers the inherited OWNER in the file system hierarchy and includes them in the entities list of authorization requests.
# Retrieve the direct and transitive owners of a specific video
g.V().hasLabel('video').has('videoId',video_id).union(in('OWNER'),repeat(out('MEMBEROF')).until(has('name', 'petVideosDirectory')).in('OWNER')).dedup().values('userId').toList()
Cedar policy design
Verified Permissions uses the Cedar policy language to define fine-grained permissions. The default decision for an authorization response is DENY. The first policy permits a principal to perform actions in the action group OwnerActions on resources in petVideosDirectory only when the same principal is included in the set of resource owners.
// Resource owner and related persons can access the resources
permit (
	principal,
	action in [PetVideosApp::Action::"OwnerActions"],
	resource in PetVideosApp::Directory::<petVideosDirectory_UUID> )
when {
	resource has owner &&
	principal in resource.owner };
The second policy is an ABAC policy that permits a principal to perform actions in the action group PublicActions on resources in petVideosDirectory only when the resource has the static attribute isPublic and its value is true.
// Allow public access to the resources
permit (
	principal,
	action in [PetVideosApp::Action::"PublicActions"],
	resource in PetVideosApp::Directory::<petVideosDirectory_UUID> )
when {
	resource has isPublic &&
	resource.isPublic == true };
Implementing ReBAC using this Cedar design pattern in conjunction with a relationship graph requires the careful construction of queries. Verified Permissions will validate that the Cedar policies are correct, based on the Cedar schema, but cannot validate that the Neptune queries correctly traverse the graph to return the correct set of principals with the referenced relationship.
When designing your policies and queries, take account of the following guidelines.
Each Cedar policy governs the behaviors of a specific relationship, in this case OWNER. Use a distinct Cedar policy for each relationship in your use cases.
Define action groups for each relationship in your use cases.
Each new relationship referenced in a Cedar policy requires its own query, and the application needs to run this query if the relationship is relevant to the authorization request. Policy writers must collaborate closely with the application developer to help ensure that the application fetches all data that’s relevant to the authorization request.
Indirect relationships can be hard to intuit and prone to errors. The example here of an OWNER relationship inherited through the MEMBEROF relationship is relatively intuitive. However, we recommend avoiding policies that rely on indirect relationships that are derived from multiple different types of direct relationship.
Indirect relationships can be over-permissive when there is no permission boundary defined. In our example, the boundary for inherited relationship is defined at the root level of the directory (petVideosDirectory). Follow the least privilege principle to limit inherited relationship within a clearly defined permission boundary.
Use MEMBEROF to denote the parent relationship in your graph to align with Cedar policy terminology. However, remember that Verified Permissions cannot auto-discover the Neptune graph, so your queries will still need to be designed to traverse it correctly.
Authorization request to Verified Permissions
The following example shows the structure of an authorization request made to Verified Permissions. In the example, Amazon Cognito is used as the identity source of the Verified Permissions policy store. Cognito user ID claims are mapped to the user entity PetVideosApp::User. Tokens issued by Cognito are mapped to a principal ID in the format <user pool ID>|<sub> by Verified Permissions.
The following request was made for action ViewVideo to the video resource entity with UUID 878c101a-ca0e-4733-904d-af3f252abf50 (the video ID of aliceCatVideo.mp4) using the ID token of alice. The user IDs for alice and charlie were returned after traversing the relationship graph in Neptune to fetch users with the OWNER relationship and include these in the owner attribute in the entities field. The entities field is an array of attributes that Verified Permissions can examine when evaluating the policies. The resource hierarchy of this video resource was shown by including the parent directories (petVideosDirectory and aliceVideosDirectory) as the parent entities in the authorization request.
With reference to the Cedar policy <Resource owner and related persons can access the resources>, the following authorization request returns an ALLOW decision.
ReBAC policies are a great fit when you want to create access based on a relationship between the principal and the resource. However, there can be cases where an ABAC policy is a more intuitive expression of a business rule. For example, in the sample application, you might want to grant all principals permission to view any public resource.
With ReBAC, you would need to create a vertex public in the relationship graph, create MEMBEROF relationships between all public resources and this vertex, and then create a VIEWER relationship between all principals and the vertex public.
With Cedar, you can create a policy store that is a mix of ReBAC and ABAC policies, enabling you to express this access rule with a single ABAC policy that allows public access to resources, as described in the section Cedar Policy Design. This policy grants broad access on resources with the attribute isPublic set to true.
You can use the following Gremlin query to modify the static property isPublic of the video resource vertex bobDogVideo.mp4 to true.
# Set the property "isPublic" to "true" for a specific video
g.V().hasLabel('video').has('name','bobDogVideo.mp4').property(single,'isPublic',true)
You can verify the value of property isPublic of bobDogVideo.mp4 with the following Gremlin query.
# Verify the value of property "isPublic" of a specific video
g.V().hasLabel('video').has('name','bobDogVideo.mp4').values('isPublic')
The following authorization request is made to Verified Permissions using the principal alice after you have set the isPublic property of the video resource bobDogVideo.mp4. In the entities field, there is the attribute isPublic with true as the value.
With reference to the Cedar policy <Allow public access to the resources>, the following authorization request returns ALLOW.
In this post, we showed you what ReBAC is and its benefits and demonstrated the implementation of ReBAC using Amazon Verified Permissions and Amazon Neptune. We also reviewed Cedar policy design patterns and considerations, in addition to the authorization request structure for a ReBAC application. You also saw how to combine ReBAC policies with ABAC policies.
Online Analytical Processing (OLAP) is crucial in modern data-driven apps, acting as an abstraction layer connecting raw data to users for efficient analysis. It organizes data into user-friendly structures, aligning with shared business definitions, ensuring users can analyze data with ease despite changes. OLAP combines data from various data sources and aggregates and groups them as business terms and KPIs. In essence, it’s the foundation for user-centric data analysis in modern apps, because it’s the layer that translates technical assets into business-friendly terms that enable users to extract actionable insights from data.
Real-time OLAP
Traditionally, OLAP datastores were designed for batch processing to serve internal business reports. The scope of data analytics has grown, and more user personas are now seeking to extract insights themselves. These users often prefer to have direct access to the data and the ability to analyze it independently, without relying solely on scheduled updates or reports provided at fixed intervals. This has led to the emergence of real-time OLAP solutions, which are particularly relevant in the following use cases:
User-facing analytics – Incorporating analytics into products or applications that consumers use to gain insights, sometimes referred to as data products.
Business metrics – Providing KPIs, scorecards, and business-relevant benchmarks.
Anomaly detection – Identifying outliers or unusual behavior patterns.
Internal dashboards – Providing analytics that are relevant to stakeholders across the organization for internal use.
Queries – Offering subsets of data to users based on their roles and security levels, allowing them to manipulate data according to their specific requirements.
Overview of Apache Pinot
Building these capabilities in real time means that real-time OLAP solutions have stricter SLAs and larger scalability requirements than traditional OLAP datastores. Accordingly, a purpose-built solution is needed to address these new requirements.
Apache Pinot is an open source real-time distributed OLAP datastore designed to meet these requirements, including low latency (tens of milliseconds), high concurrency (hundreds of thousands of queries per second), near real-time data freshness, and handling petabyte-scale data volumes. It ingests data from both streaming and batch sources and organizes it into logical tables distributed across multiple nodes in a Pinot cluster, ensuring scalability.
Pinot provides functionality similar to other modern big data frameworks, supporting SQL queries, upserts, complex joins, and various indexing options.
Pinot has been tested at very large scale in large enterprises, serving over 70 LinkedIn data products, handling over 120,000 Queries Per Second (QPS), ingesting over 1.5 million events per second, and analyzing over 10,000 business metrics across over 50,000 dimensions. A notable use case is the user-facing Uber Eats Restaurant Manager dashboard, serving over 500,000 users with instant insights into restaurant performance.
Pinot clusters are designed for high availability, horizontal scalability, and live configuration changes without impacting performance. To that end, Pinot is architected as a distributed datastore to enable all of the above requirements, and utilizes similar architectural constructs as Apache Kafka and Apache Hadoop in its design.
Solution overview
In this, we will provide a step-by-step guide showing you how you can build a real-time OLAP datastore on Amazon Web Services (AWS) using Apache Pinot on Amazon Elastic Compute Cloud (Amazon EC2) and do near real-time visualization using Tableau. You can use Apache Pinot for batch processing use cases as well but, in this post, we will focus on a near real-time analytics use case.
You can use Amazon Managed Service for Apache Flink service. The objective in the preceding figure is to ingest streaming data into Pinot, where it can perform.
The objective in the preceding figure is to ingest streaming data into Pinot, where it can perform aggregations, update current data models, and serve OLAP queries in real time to consuming users and applications, which in this case is a user-facing Tableau dashboard.
The data flow as follows:
Data is ingested from a real-time source, such as clickstream data from a website. For the purposes of this post, we will use the Amazon Kinesis Data Generator to simulate the production of events.
The events are then ingested into the real-time server within Apache Pinot, which is used to process data coming from streaming sources, such as MSK and KDS. Apache Pinot consists of logical tables, which are partitioned into segments. Due to the time sensitive nature of streaming, events are directly written into memory as consuming segments, which can be thought of as parts of an active table that are continuously ingesting new data. Consuming segments are available for query processing immediately, thereby enabling low latency and high data freshness.
After the segments reach a threshold in terms of time or number of rows, they are moved into Amazon Simple Storage Service (Amazon S3), which serves as deep storage for the Apache Pinot cluster. Deep storage is the permanent location for segment files. Segments used for batch processing are also stored there.
In parallel, the Pinot controller tracks the metadata of the cluster and performs actions required to keep the cluster in an ideal state. Its primary function is to orchestrate cluster resources as well as manage connections between resources within the cluster and data sources outside of it. Under the hood, the controller uses Apache Helix to manage cluster state, failover, distribution, and scalability and Apache Zookeeper to handles distributed coordination functions such as leader election, locks, queue management, and state tracking.
To enable the distributed aspect of the Pinot architecture, the broker accepts queries from the clients and forwards them to servers and collects the results and sends them back. The broker manages and optimizes the queries, distributes them across the servers, combines the results, and returns the result set. The broker sends the request to the right segments on the right servers, optimizes segment pruning, and splits the queries across servers appropriately. The results of each query are then merged and sent back to the requesting client.
The results of the queries are updated in real time in the Tableau dashboard.
To ensure high availability, the solution deploys application load balancers for the brokers and servers. We can access the Apache Pinot UI using the controller load balancer and use it to run queries and monitor the Apache Pinot cluster
Let’s start to deploy this solution and perform near real-time visualizations using Apache Pinot and Tableau.
Prerequisites
Before you get started, make sure you have the following prerequisites:
Install Kinesis data generator (KDG) using AWS CloudFormation by following the instructions to stream sample web transactions into the Kinesis data stream. The KDG makes it easy to send data to a Kinesis data stream.
Copy the drivers to the C:\Program Files\Tableau\Drivers folder when using Tableau Desktop on Windows. For other operating systems, see the instructions.
Ensure all CloudFormation and AWS Cloud Development Kit (AWS CDK) templates are deployed in the same AWS Region for all resources throughout the following steps.
Deploy the Apache Pinot solution using the AWS CDK
The AWS CDK is an open source project that you can use to define your cloud infrastructure using familiar programming languages. It uses high-level constructs to represent AWS components to simplify the build process. In this post, we use TypeScript and Python to define the cloud infrastructure.
First, bootstrap the AWS CDK. This sets up the resources required by the AWS CDK to deploy into the AWS account. This step is only required if you haven’t used the AWS CDK in the deployment account and Region. The format for the bootstrap command is cdk bootstrap aws://<account-id>/<aws-region>.
In the following example, I’m running a bootstrap command for a fictitious AWS account with ID 123456789000 and us-east-1 N.Virginia Region:
cdk bootstrap aws://123456789000/us-east-1
Next, clone the GitHub repository and install all the dependencies from package.json by running the following commands from the root of the cloned repository.
git clonehttps://github.com/aws-samples/near-realtime-apache-pinot-workshop

cd near-realtime-apache-pinot-workshop

npm i
Deploy the AWS CDK stack to create the AWS Cloud infrastructure by running the following command and enter y when prompted. Enter the IP address that you want to use to access the Apache Pinot controller and broker in /32 subnet mask format.
Deployment of the AWS CDK stack takes approximately 10–12 minutes. You should see a stack deployment message that will display the creation of AWS objects, followed by the deployment time, the Stack ARN, and the total time, similar to the following screenshot:
Now, you can get the Apache Pinot controller Application Load Balancer (ALB) DNS name from the Copy the value for ControllerDNSUrl.
Launch a browser session and paste the DNS name to see the Apache Pinot controller—it should look like the following screenshot, where you will see:
Number of controllers, brokers, servers, minions, tenants, and tables
List of tenants
List of controllers
List of brokers
Near real-time visualization using Tableau
Now that we have provisioned all AWS Cloud resources, we will stream some sample web transactions to a Kinesis data stream and visualize the data in near real time from Tableau Desktop.
You can follow these steps to open the Tableau workbook to visualize
Download the Tableau workbook to your local machine and open the workbook from Tableau Desktop.
Get the DNS name for Apache Pinot broker’s Application Load Balancer DNS name from the CloudFormation console. Choose Stacks, select the ApachePinotSolutionStack, and then choose Outputs and copy the value for BrokerDNSUrl.
Choose Edit connection and enter the URL in the following format:
Access the KDG tool by following the instructions. Use the record template that follows to send sample web transactions data to Kinesis Data streams called pinot-stream by choosing Send dataas shown in the following screenshot. Stop sending data after sending a handful of records by choosing Stop sending data to Kinesis.
You should be able to see the web transactions data in Tableau Desktop as shown in the following screenshot.
Clean up
To clean up the AWS resources you created:
Disable termination protection on the following EC2 instances by going to the Amazon EC2 console and choosing Instance from the navigation pane. Choose Actions, Instance Settings, and then Change termination protection and clear the Termination protection checkbox.
ApachePinotSolutionStack/bastionHost
ApachePinotSolutionStack/zookeeperNode1
ApachePinotSolutionStack/zookeeperNode2
ApachePinotSolutionStack/zookeeperNode3
Run the following command from the cloned GitHub repo and enter y when prompted.
cdk destroy
Scaling the solution to production
The example in this post uses minimal resources to demonstrate functionality. Taking this to production requires a higher level of scalability. The solution provides autoscaling policies for independently scaling brokers and servers in and out, allowing the Apache Pinot custer to scale based on CPU requirements.
When autoscaling is initiated, the solution will invoke an AWS Lambda Function, to run the logic needed to add or remove brokers and servers in Apache Pinot.
In Apache Pinot, tables are tagged with an identifier that’s used for routing queries to the appropriate servers. When creating a table, you can specify a table name and optionally tag it. This is useful when you want to route queries to specific servers or build a multi-tenant Apache Pinot cluster. However, tagging adds additional considerations when removing brokers or servers. You need to make sure that neither have any active tables or tags associated with them. And when adding new components, rebalance the segments, so you can use the new brokers and servers.
Therefore, when scaling is needed in the solution, the autoscaling policy will invoke a Lambda function that either rebalances the segments of the tables when you add a new broker or server, or removes any tags associated with the broker or server you remove from the cluster.
Summary
Just like you would commonly use a distributed NoSQL datastore to serve a mobile application that requires low latency, high concurrency, high data freshness, high data volume, and high throughput, a distributed real-time OLAP datastore like Apache Pinot is purpose-built for achieving the same requirements for the analytics workload within your user-facing application. In this post, we walked you through how to deploy a scalable Apache Pinot-based near real-time user facing analytics solution on AWS. If you have any questions or suggestions, write to us in the comments section
About the authors
Raj Ramasubbu is a Senior Analytics Specialist Solutions Architect focused on big data and analytics and AI/ML with Amazon Web Services. He helps customers architect and build highly scalable, performant, and secure cloud-based solutions on AWS. Raj provided technical expertise and leadership in building data engineering, big data analytics, business intelligence, and data science solutions for over 18 years prior to joining AWS. He helped customers in various industry verticals like healthcare, medical devices, life science, retail, asset management, car insurance, residential REIT, agriculture, title insurance, supply chain, document management, and real estate.
Francisco Morillo is a Streaming Solutions Architect at AWS. Francisco works with AWS customers, helping them design real-time analytics architectures using AWS services, supporting Amazon Managed Streaming for Apache Kafka (Amazon MSK) and Amazon Managed Service for Apache Flink.
Ismail Makhlouf is a Senior Specialist Solutions Architect for Data Analytics at AWS. Ismail focuses on architecting solutions for organizations across their end-to-end data analytics estate, including batch and real-time streaming, big data, data warehousing, and data lake workloads. He primarily partners with airlines, manufacturers, and retail organizations to support them to achieve their business objectives with well-architected data platforms.
Since the launch of tiered storage for Amazon Managed Streaming for Apache Kafka (Amazon MSK), customers have embraced this feature for its ability to optimize storage costs and improve performance. In previous posts, we explored the inner workings of Kafka, maximized the potential of Amazon MSK, and delved into the intricacies of Amazon MSK tiered storage. In this post, we deep dive into how tiered storage helps with faster broker recovery and quicker partition migrations, facilitating faster load balancing and broker scaling.
Apache Kafka availability
Apache Kafka is a distributed log service designed to provide high availability and fault tolerance. At its core, Kafka employs several mechanisms to provide reliable data delivery and resilience against failures:
Kafka replication – Kafka organizes data into topics, which are further divided into partitions. Each partition is replicated across multiple brokers, with one broker acting as the leader and the others as followers. If the leader broker fails, one of the follower brokers is automatically elected as the new leader, providing continuous data availability. The replication factor determines the number of replicas for each partition. Kafka maintains a list of in-sync replicas (ISRs) for each partition, which are the replicas that are up to date with the leader.
Producer acknowledgments – Kafka producers can specify the required acknowledgment level for write operations. This makes sure the data is durably persisted on the configured number of replicas before the producer receives an acknowledgment, reducing the risk of data loss.
Consumer group rebalancing – Kafka consumers are organized into consumer groups, where each consumer in the group is responsible for consuming a subset of the partitions. If a consumer fails, the partitions it was consuming are automatically reassigned to the remaining consumers in the group, providing continuous data consumption.
Zookeeper or KRaft for cluster coordination – Kafka relies on Apache ZooKeeper or KRaft for cluster coordination and metadata management. It maintains information about brokers, topics, partitions, and consumer offsets, enabling Kafka to recover from failures and maintain a consistent state across the cluster.
Kafka’s storage architecture and its impact on availability and resiliency
Although Kafka provides robust fault-tolerance mechanisms, in the traditional Kafka architecture, brokers store data locally on their attached storage volumes. This tight coupling of storage and compute resources can lead to several issues, impacting availability and resiliency of the cluster:
Slow broker recovery – When a broker fails, the recovery process involves transferring data from the remaining replicas to the new broker. This data transfer can be slow, especially for large data volumes, leading to prolonged periods of reduced availability and increased recovery times.
Inefficient load balancing – Load balancing in Kafka involves moving partitions between brokers to distribute the load evenly. However, this process can be resource-intensive and time-consuming, because it requires transferring large amounts of data between brokers.
Scaling limitations – Scaling a Kafka cluster traditionally involves adding new brokers and rebalancing partitions across the expanded set of brokers. This process can be disruptive and time-consuming, especially for large clusters with high data volumes.
How Amazon MSK tiered storage improves availability and resiliency
Amazon MSK offers tiered storage, a feature that allows configuring local and remote tiers. This greatly decouples compute and storage resources and thereby addresses the aforementioned challenges, improving availability and resiliency of Kafka clusters. You can benefit from the following:
Faster broker recovery – With tiered storage, data automatically moves from the faster Amazon Elastic Block Store (Amazon EBS) volumes to the more cost-effective storage tier over time. New messages are initially written to Amazon EBS for fast performance. Based on your local data retention policy, Amazon MSK transparently transitions that data to tiered storage. This frees up space on the EBS volumes for new messages. When broker fails and recovers either due to node or volume failure, the catch-up is faster because it only needs to catch up data stored on the local tier from the leader.
Efficient load balancing – Load balancing in Amazon MSK with tiered storage is more efficient because there is less data to move while reassigning partition. This process is faster and less resource-intensive, enabling more frequent and seamless load balancing operations.
Faster scaling – Scaling an MSK cluster with tiered storage is a seamless process. New brokers can be added to the cluster without the need for a large amount of data transfer and longer time for partition rebalancing. The new brokers can start serving traffic much faster, because the catch-up process takes less time, improving the overall cluster throughput and reducing downtime during scaling operations.
As shown in the following figure, MSK brokers and EBS volumes are tightly coupled. On a three-AZ deployed cluster, when you create a topic with replication factor three, Amazon MSK spreads those three replicas across all three Availability Zones and the EBS volumes attached with that broker store all the topic data spread across three Availability Zones. If you need to move a partition from one broker to another, Amazon MSK needs to move all the segments (both active and closed) from the existing broker to the new brokers, as illustrated in the following figure.
However, when you enable tiered storage for that topic, Amazon MSK transparently moves all closed segments for a topic from EBS volumes to tiered storage. That storage provides the built-in capability for durability and high availability with virtually unlimited storage capacity. With closed segments moved to tiered storage and only active segments on the local volume, your local storage footprint remains minimal regardless of topic size. If you need to move the partition to a new broker, the data movement is very minimal across the brokers. The following figure illustrates this updated configuration.
Amazon MSK tiered storage addresses the challenges posed by Kafka’s traditional storage architecture, enabling faster broker recovery, efficient load balancing, and seamless scaling, thereby improving availability and resiliency of your cluster. To learn more about the core components of Amazon MSK tiered storage, refer to Deep dive on Amazon MSK tiered storage.
A real-world test
We hope that you now understand how Amazon MSK tiered storage can improve your Kafka resiliency and availability. To test it, we created a three-node cluster with the new m7g instance type. We created a topic with a replication factor of three and without using tiered storage. Using the Kafka performance tool, we ingested 300 GB of data into the topic. Next, we added three new brokers to the cluster. Because Amazon MSK doesn’t automatically move partitions to these three new brokers, they will remain idle until we rebalance the partitions across all six brokers.
Let’s consider a scenario where we need to move all the partitions from the existing three brokers to the three new brokers. We used the kafka-reassign-partitions tool to move the partitions from the existing three brokers to the newly added three brokers. During this partition movement operation, we observed that the CPU usage was high, even though we weren’t performing any other operations on the cluster. This indicates that the high CPU usage was due to the data replication to the new brokers. As shown in the following metrics, the partition movement operation from broker 1 to broker 2 took approximately 75 minutes to complete.
Additionally, during this period, CPU utilization was elevated.
After completing the test, we enabled tiered storage on the topic with local.retention.ms=3600000 (1 hour) and retention.ms=31536000000. We continuously monitored the RemoteCopyBytesPerSec metrics to determine when the data migration to tiered storage was complete. After 6 hours, we observed zero activity on the RemoteCopyBytesPerSec metrics, indicating that all closed segments had been successfully moved to tiered storage. For instructions to enable tiered storage on an existing topic, refer to Enabling and disabling tiered storage on an existing topic.
We then performed the same test again, moving partitions to three empty brokers. This time, the partition movement operation was completed in just under 15 minutes, with no noticeable CPU usage, as shown in the following metrics. This is because, with tiered storage enabled, all the data has already been moved to the tiered storage, and we only have the active segment in the EBS volume. The partition movement operation is only moving the small active segment, which is why it takes less time and minimal CPU to complete the operation.
Conclusion
In this post, we explored how Amazon MSK tiered storage can significantly improve the scalability and resilience of Kafka. By automatically moving older data to the cost-effective tiered storage, Amazon MSK reduces the amount of data that needs to be managed on the local EBS volumes. This dramatically improves the speed and efficiency of critical Kafka operations like broker recovery, leader election, and partition reassignment. As demonstrated in the test scenario, enabling tiered storage reduced the time taken to move partitions between brokers from 75 minutes to just under 15 minutes, with minimal CPU impact. This enhanced the responsiveness and self-healing ability of the Kafka cluster, which is crucial for maintaining reliable, high-performance operations, even as data volumes continue to grow.
If you’re running Kafka and facing challenges with scalability or resilience, we highly recommend using Amazon MSK with the tiered storage feature. By taking advantage of this powerful capability, you can unlock the true scalability of Kafka and make sure your mission-critical applications can keep pace with ever-increasing data demands.
Sai Maddali is a Senior Manager Product Management at AWS who leads the product team for Amazon MSK. He is passionate about understanding customer needs, and using technology to deliver services that empowers customers to build innovative applications. Besides work, he enjoys traveling, cooking, and running.
Nagarjuna Koduru is a Principal Engineer in AWS, currently working for AWS Managed Streaming For Kafka (MSK). He led the teams that built MSK Serverless and MSK Tiered storage products. He previously led the team in Amazon JustWalkOut (JWO) that is responsible for real time tracking of shopper locations in the store. He played pivotal role in scaling the stateful stream processing infrastructure to support larger store formats and reducing the overall cost of the system. He has keen interest in stream processing, messaging and distributed storage infrastructure.
Masudur Rahaman Sayem is a Streaming Data Architect at AWS. He works with AWS customers globally to design and build data streaming architectures to solve real-world business problems. He specializes in optimizing solutions that use streaming data services and NoSQL. Sayem is very passionate about distributed computing.
This post was co-written with Balaram Mathukumilli, Viswanatha Vellaboyana and Keerthi Kambam from DISH Wireless, a wholly owned subsidiary of EchoStar.
Amazon Redshift Serverless is a fully managed, scalable cloud data warehouse that accelerates your time to insights with fast, simple, and secure analytics at scale. Amazon Redshift data sharing allows you to share data within and across organizations, AWS Regions, and even third-party providers, without moving or copying the data. Additionally, it allows you to use multiple warehouses of different types and sizes for extract, transform, and load (ETL) jobs so you can tune your warehouses based on your write workloads’ price-performance needs.
You can use the Amazon Redshift Streaming Ingestion capability to update your analytics data warehouse in near real time. Redshift Streaming Ingestion simplifies data pipelines by letting you create materialized views directly on top of data streams. With this capability in Amazon Redshift, you can use SQL to connect to and directly ingest data from data streams, such as Amazon Kinesis Data Streams or Amazon Managed Streaming for Apache Kafka (Amazon MSK), and pull data directly to Amazon Redshift.
EchoStar uses Redshift Streaming Ingestion to ingest over 10 TB of data daily from more than 150 MSK topics in near real time across its Open RAN 5G network. This post provides an overview of real-time data analysis with Amazon Redshift and how EchoStar uses it to ingest hundreds of megabytes per second. As data sources and volumes grew across its network, EchoStar migrated from a single Redshift Serverless workgroup to a multi-warehouse architecture with live data sharing. This resulted in improved performance for ingesting and analyzing their rapidly growing data.
“By adopting the strategy of ‘parse and transform later,’ and establishing an Amazon Redshift data warehouse farm with a multi-cluster architecture, we leveraged the power of Amazon Redshift for direct streaming ingestion and data sharing.
“This innovative approach improved our data latency, reducing it from two–three days to an average of 37 seconds. Additionally, we achieved better scalability, with Amazon Redshift direct streaming ingestion supporting over 150 MSK topics.”
—Sandeep Kulkarni, VP, Software Engineering & Head of Wireless OSS Platforms at EchoStar
EchoStar use case
EchoStar needed to provide near real-time access to 5G network performance data for downstream consumers and interactive analytics applications. This data is sourced from the 5G network EMS observability infrastructure and is streamed in near real-time using AWS services like AWS Lambda and AWS Step Functions. The streaming data produced many small files, ranging from bytes to kilobytes. To efficiently integrate this data, a messaging system like Amazon MSK was required.
EchoStar was processing over 150 MSK topics from their messaging system, with each topic containing around 1 billion rows of data per day. This resulted in an average total data volume of 10 TB per day. To use this data, EchoStar needed to visualize it, perform spatial analysis, join it with third-party data sources, develop end-user applications, and use the insights to make near real-time improvements to their terrestrial 5G network. EchoStar needed a solution that does the following:
Optimize parsing and loading of over 150 MSK topics to enable downstream workloads to run simultaneously without impacting each other
Allow hundreds of queries to run in parallel with desired query throughput
Seamlessly scale capacity with the increase in user base and maintain cost-efficiency
Solution overview
EchoStar migrated from a single Redshift Serverless workgroup to a multi-warehouse Amazon Redshift architecture in partnership with AWS. The new architecture enables workload isolation by separating streaming ingestion and ETL jobs from analytics workloads across multiple Redshift compute instances. At the same time, it provides live data sharing using a single copy of the data between the data warehouse. This architecture takes advantage of AWS capabilities to scale Redshift streaming ingestion jobs and isolate workloads while maintaining data access.
The following diagram shows the high-level end-to-end serverless architecture and overall data pipeline.
The solution consists of the following key components:
Primary ETL Redshift Serverless workgroup – A primary ETL producer workgroup of size 392 RPU
Secondary Redshift Serverless workgroups – Additional producer workgroups of varying sizes to distribute and scale near real-time data ingestion from over 150 MSK topics based on price-performance requirements
Consumer Redshift Serverless workgroup – A consumer workgroup instance to run analytics using Tableau
To efficiently load multiple MSK topics into Redshift Serverless in parallel, we first identified the topics with the highest data volumes in order to determine the appropriate sizing for secondary workgroups.
We began by sizing the system initially to Redshift Serverless workgroup of 64 RPU. Then we onboarded a small number of MSK topics, creating related streaming materialized views. We incrementally added more materialized views, evaluating overall ingestion cost, performance, and latency needs within a single workgroup. This initial benchmarking gave us a solid baseline to onboard the remaining MSK topics across multiple workgroups.
In addition to a multi-warehouse approach and workgroup sizing, we optimized such large-scale data volume ingestion with an average latency of 37 seconds by splitting ingestion jobs into two steps:
Streaming materialized views – Use JSON_PARSE to ingest data from MSK topics in Amazon Redshift
Flattening materialized views – Shred and perform transformations as a second step, reading data from the respective streaming materialized view
The following diagram depicts the high-level approach.
Best practices
In this section, we share some of the best practices we observed while implementing this solution:
We performed an initial Redshift Serverless workgroup sizing based on three key factors:
Number of records per second per MSK topic
Average record size per MSK topic
Desired latency SLA
Additionally, we created only one streaming materialized view for a given MSK topic. Creation of multiple materialized views per MSK topic can slow down the ingestion performance because each materialized view becomes a consumer for that topic and shares the Amazon MSK bandwidth for that topic.
While defining the streaming materialized view, we avoided using JSON_EXTRACT_PATH_TEXT to pre-shred data, because json_extract_path_text operates on the data row by row, which significantly impacts ingestion throughput. Instead, we adopted JSON_PARSE with the CAN_JSON_PARSE function to ingest data from the stream at lowest latency and to guard against errors. The following is a sample SQL query we used for the MSK topics (the actual data source names have been masked due to security reasons):
CREATE MATERIALIZED VIEW <source-name>_streaming_mvw AUTO REFRESH YES AS
SELECT
    kafka_partition,
    kafka_offset,
    refresh_time,
    case when CAN_JSON_PARSE(kafka_value) = true then JSON_PARSE(kafka_value) end as Kafka_Data,
    case when CAN_JSON_PARSE(kafka_value) = false then kafka_value end as Invalid_Data
FROM
    external_<source-name>."<source-name>_mvw";
We kept the streaming materialized views simple and moved all transformations like unnesting, aggregation, and case expressions to a later step as flattening materialized views. The following is a sample SQL query we used to flatten data by reading the streaming materialized views created in the previous step (the actual data source and column names have been masked due to security reasons):
CREATE MATERIALIZED VIEW <source-name>_flatten_mvw AUTO REFRESH NO AS
SELECT
    kafka_data."<column1>" :: integer as "<column1>",
    kafka_data."<column2>" :: integer as "<column2>",
    kafka_data."<column3>" :: bigint as "<column3>",
    …
    …
    …
    …
FROM
    <source-name>_streaming_mvw;
The streaming materialized views were set to auto refresh so that they can continuously ingest data into Amazon Redshift from MSK topics.
EchoStar saw improvements with this solution in both performance and scalability across their 5G Open RAN network.
Performance
By isolating and scaling Redshift Streaming Ingestion refreshes across multiple Redshift Serverless workgroups, EchoStar met their latency SLA requirements. We used the following SQL query to measure latencies:
WITH curr_qry as (
    SELECT
        mv_name,
        cast(partition_id as int) as partition_id,
        max(query_id) as current_query_id
    FROM
        sys_stream_scan_states
    GROUP BY
        mv_name,
        cast(partition_id as int)
)
SELECT
    strm.mv_name,
    tmp.partition_id,
    min(datediff(second, stream_record_time_max, record_time)) as min_latency_in_secs,
    max(datediff(second, stream_record_time_min, record_time)) as max_latency_in_secs
FROM
    sys_stream_scan_states strm,
    curr_qry tmp
WHERE
    strm.query_id = tmp.current_query_id
    and strm.mv_name = tmp.mv_name
    and strm.partition_id = tmp.partition_id
GROUP BY 1,2
ORDER BY 1,2;
When we further aggregate the preceding query to only the mv_name level (removing partition_id, which uniquely identifies a partition in an MSK topic), we find the average daily performance results we achieved on a Redshift Serverless workgroup size of 64 RPU as shown in the following chart. (The actual materialized view names have been hashed for security reasons because it maps to an external vendor name and data source.)
S.No.
stream_name_hash
min_latency_secs
max_latency_secs
avg_records_per_day
1
e022b6d13d83faff02748d3762013c
1
6
186,395,805
2
a8cc0770bb055a87bbb3d37933fc01
1
6
186,720,769
3
19413c1fc8fd6f8e5f5ae009515ffb
2
4
5,858,356
4
732c2e0b3eb76c070415416c09ffe0
3
27
12,494,175
5
8b4e1ffad42bf77114ab86c2ea91d6
3
4
149,927,136
6
70e627d11eba592153d0f08708c0de
5
5
121,819
7
e15713d6b0abae2b8f6cd1d2663d94
5
31
148,768,006
8
234eb3af376b43a525b7c6bf6f8880
6
64
45,666
9
38e97a2f06bcc57595ab88eb8bec57
7
100
45,666
10
4c345f2f24a201779f43bd585e53ba
9
12
101,934,969
11
a3b4f6e7159d9b69fd4c4b8c5edd06
10
14
36,508,696
12
87190a106e0889a8c18d93a3faafeb
13
69
14,050,727
13
b1388bad6fc98c67748cc11ef2ad35
25
118
509
14
cf8642fccc7229106c451ea33dd64d
28
66
13,442,254
15
c3b2137c271d1ccac084c09531dfcd
29
74
12,515,495
16
68676fc1072f753136e6e992705a4d
29
69
59,565
17
0ab3087353bff28e952cd25f5720f4
37
71
12,775,822
18
e6b7f10ea43ae12724fec3e0e3205c
39
83
2,964,715
19
93e2d6e0063de948cc6ce2fb5578f2
45
45
1,969,271
20
88cba4fffafd085c12b5d0a01d0b84
46
47
12,513,768
21
d0408eae66121d10487e562bd481b9
48
57
12,525,221
22
de552412b4244386a23b4761f877ce
52
52
7,254,633
23
9480a1a4444250a0bc7a3ed67eebf3
58
96
12,522,882
24
db5bd3aa8e1e7519139d2dc09a89a7
60
103
12,518,688
25
e6541f290bd377087cdfdc2007a200
71
83
176,346,585
26
6f519c71c6a8a6311f2525f38c233d
78
115
100,073,438
27
3974238e6aff40f15c2e3b6224ef68
79
82
12,770,856
28
7f356f281fc481976b51af3d76c151
79
96
75,077
29
e2e8e02c7c0f68f8d44f650cd91be2
92
99
12,525,210
30
3555e0aa0630a128dede84e1f8420a
97
105
8,901,014
31
7f4727981a6ba1c808a31bd2789f3a
108
110
11,599,385
All 31 materialized views running and refreshing concurrently and continuously show a minimum latency of 1 second and a maximum latency of 118 seconds over the last 7 days, meeting EchoStar’s SLA requirements.
Scalability
With this Redshift data sharing enabled multi-warehouse architecture approach, EchoStar can now quickly scale their Redshift compute resources on demand by using the Redshift data sharing architecture to onboard the remaining 150 MSK topics. In addition, as their data sources and MSK topics increase further, they can quickly add additional Redshift Serverless workgroups (for example, another Redshift Serverless 128 RPU workgroup) to meet their desired SLA requirements.
Conclusion
By using the scalability of Amazon Redshift and a multi-warehouse architecture with data sharing, EchoStar delivers near real-time access to over 150 million rows of data across over 150 MSK topics, totaling 10 TB ingested daily, to their users.
This split multi-producer/consumer model of Amazon Redshift can bring benefits to many workloads that have similar performance characteristics as EchoStar’s warehouse. With this pattern, you can scale your workload to meet SLAs while optimizing for price and performance. Please reach out to your AWS Account Team to engage an AWS specialist for additional help or for a proof of concept.
About the authors
Balaram Mathukumilli is Director, Enterprise Data Services at DISH Wireless. He is deeply passionate about Data and Analytics solutions. With 20+ years of experience in Enterprise and Cloud transformation, he has worked across domains such as PayTV, Media Sales, Marketing and Wireless. Balaram works closely with the business partners to identify data needs, data sources, determine data governance, develop data infrastructure, build data analytics capabilities, and foster a data-driven culture to ensure their data assets are properly managed, used effectively, and are secure
Viswanatha Vellaboyana, a Solutions Architect at DISH Wireless, is deeply passionate about Data and Analytics solutions. With 20 years of experience in enterprise and cloud transformation, he has worked across domains such as Media, Media Sales, Communication, and Health Insurance. He collaborates with enterprise clients, guiding them in architecting, building, and scaling applications to achieve their desired business outcomes.
Keerthi Kambam is a Senior Engineer at DISH Network specializing in AWS Services. She builds scalable data engineering and analytical solutions for dish customer faced applications. She is passionate about solving complex data challenges with cloud solutions.
Raks Khare is a Senior Analytics Specialist Solutions Architect at AWS based out of Pennsylvania. He helps customers across varying industries and regions architect data analytics solutions at scale on the AWS platform. Outside of work, he likes exploring new travel and food destinations and spending quality time with his family.
Adi Eswar has been a core member of the AI/ML and Analytics Specialist team, leading the customer experience of customer’s existing workloads and leading key initiatives as part of the Analytics Customer Experience Program and Redshift enablement in AWS-TELCO customers. He spends his free time exploring new food, cultures, national parks and museums with his family.
Shirin Bhambhani is a Senior Solutions Architect at AWS. She works with customers to build solutions and accelerate their cloud migration journey. She enjoys simplifying customer experiences on AWS.
Vinayak Rao is a Senior Customer Solutions Manager at AWS. He collaborates with customers, partners, and internal AWS teams to drive customer success, delivery of technical solutions, and cloud adoption.
Multimodal search enables both text and image search capabilities, transforming how users access data through search applications. Consider building an online fashion retail store: you can enhance the users’ search experience with a visually appealing application that customers can use to not only search using text but they can also upload an image depicting a desired style and use the uploaded image alongside the input text in order to find the most relevant items for each user. Multimodal search provides more flexibility in deciding how to find the most relevant information for your search.
To enable multimodal search across text, images, and combinations of the two, you generate embeddings for both text-based image metadata and the image itself. Text embeddings capture document semantics, while image embeddings capture visual attributes that help you build rich image search applications.
Amazon Titan Multimodal Embeddings G1 is a multimodal embedding model that generates embeddings to facilitate multimodal search. These embeddings are stored and managed efficiently using specialized vector stores such as Amazon OpenSearch Service, which is designed to store and retrieve large volumes of high-dimensional vectors alongside structured and unstructured data. By using this technology, you can build rich search applications that seamlessly integrate text and visual information.
Amazon OpenSearch Service and Amazon OpenSearch Serverless support the vector engine, which you can use to store and run vector searches. In addition, OpenSearch Service supports neural search, which provides out-of-the-box machine learning (ML) connectors. These ML connectors enable OpenSearch Service to seamlessly integrate with embedding models and large language models (LLMs) hosted on Amazon Bedrock, Amazon SageMaker, and other remote ML platforms such as OpenAI and Cohere. When you use the neural plugin’s connectors, you don’t need to build additional pipelines external to OpenSearch Service to interact with these models during indexing and searching.
This blog post provides a step-by-step guide for building a multimodal search solution using OpenSearch Service. You will use ML connectors to integrate OpenSearch Service with the Amazon Bedrock Titan Multimodal Embeddings model to infer embeddings for your multimodal documents and queries. This post illustrates the process by showing you how to ingest a retail dataset containing both product images and product descriptions into your OpenSearch Service domain and then perform a multimodal search by using vector embeddings generated by the Titan multimodal model. The code used in this tutorial is open source and available on GitHub for you to access and explore.
Multimodal search solution architecture
We will provide the steps required to set up multimodal search using OpenSearch Service. The following image depicts the solution architecture.
OpenSearch Service calls the Amazon Bedrock Titan Multimodal Embeddings model to generate multimodal vector embeddings for both the product description and image.
Through an OpenSearch Service client, you pass a search query.
OpenSearch Service calls the Amazon Bedrock Titan Multimodal Embeddings model to generate vector embedding for the search query.
OpenSearch runs the neural search and returns the search results to the client.
Let’s look at steps 1, 2, and 4 in more detail.
Step 1: Ingestion of the data into OpenSearch
This step involves the following OpenSearch Service features:
Ingest pipelines – An ingest pipeline is a sequence of processors that are applied to documents as they’re ingested into an index. Here you use a text_image_embedding processor to generate combined vector embeddings for the image and image description.
k-NN index – The k-NN index introduces a custom data type, knn_vector, which allows users to ingest vectors into an OpenSearch index and perform different kinds of k-NN searches. You use the k-NN index to store both the general field data types, such as text, numeric, etc., and specialized field data types, such as knn_vector.
Steps 2 and 4: OpenSearch calls the Amazon Bedrock Titan model
OpenSearch Service uses the Amazon Bedrock connector to generate embeddings for the data. When you send the image and text as part of your indexing and search requests, OpenSearch uses this connector to exchange the inputs with the equivalent embeddings from the Amazon Bedrock Titan model. The highlighted blue box in the architecture diagram depicts the integration of OpenSearch with Amazon Bedrock using this ML-connector feature. This direct integration eliminates the need for an additional component (for example, AWS Lambda) to facilitate the exchange between the two services.
Solution overview
In this post, you will build and run multimodal search using a sample retail dataset. You will use the same multimodal generated embeddings and experiment by running text search only, image search only and both text and image search in OpenSearch Service.
Prerequisites
Create an OpenSearch Service domain. For instructions, see Creating and managing Amazon OpenSearch Service domains. Make sure the following settings are applied when you create the domain, while leaving other settings as default.
OpenSearch version is 2.13
The domain has public access
Fine-grained access control is enabled
A master user is created
Set up a Python client to interact with the OpenSearch Service domain, preferably on a Jupyter Notebook interface.
Note that you need to refer to the Jupyter Notebook in the GitHub repository to run the following steps using Python code in your client environment. The following sections provide the sample blocks of code that contain only the HTTP request path and the request payload to be passed to OpenSearch Service at every step.
Data overview and preparation
You will be using a retail dataset that contains 2,465 retail product samples that belong to different categories such as accessories, home decor, apparel, housewares, books, and instruments. Each product contains metadata including the ID, current stock, name, category, style, description, price, image URL, and gender affinity of the product. You will be using only the product image and product description fields in the solution.
A sample product image and product description from the dataset are shown in the following image:
Figure 2: Sample product image and description
In addition to the original product image, the textual description of the image provides additional metadata for the product, such as color, type, style, suitability, and so on. For more information about the dataset, visit the retail demo store on GitHub.
Step 1: Create the OpenSearch-Amazon Bedrock ML connector
The OpenSearch Service console provides a streamlined integration process that allows you to deploy an Amazon Bedrock-ML connector for multimodal search within minutes. OpenSearch Service console integrations provide AWS CloudFormation templates to automate the steps of Amazon Bedrock model deployment and Amazon Bedrock-ML connector creation in OpenSearch Service.
In the OpenSearch Service console, navigate to Integrations as shown in the following image and search for Titan multi-modal. This returns the CloudFormation template named Integrate with Amazon Bedrock Titan Multi-modal, which you will use in the following steps.Figure 3: Configure domain
Select Configure domain and choose ‘Configure public domain’.
You will be automatically redirected to a CloudFormation template stack as shown in the following image, where most of the configuration is pre-populated for you, including the Amazon Bedrock model, the ML model name, and the AWS Identity and Access Management (IAM) role that is used by Lambda to invoke your OpenSearch domain. Update Amazon OpenSearch Endpoint with your OpenSearch domain endpoint and Model Region with the AWS Region in which your model is available.Figure 4: Create a CloudFormation stack
Before you deploy the stack by clicking ‘Create Stack’, you need to give necessary permissions for the stack to create the ML connector. The CloudFormation template creates a Lambda IAM role for you with the default name LambdaInvokeOpenSearchMLCommonsRole, which you can override if you want to choose a different name. You need to map this IAM role as a Backend role for ml_full_access role in OpenSearch dashboards Security plugin, so that the Lambda function can successfully create the ML connector. To do so,
Login to the OpenSearch Dashboards using the master user credentials that you created as a part of prerequisites. You can find the Dashboards endpoint on your domain dashboard on the OpenSearch Service console.
From the main menu choose Security, Roles, and select the ml_full_access role.
Choose Mapped users, Manage mapping.
Under Backend roles, add the ARN of the Lambda role (arn:aws:iam::<account-id>:role/LambdaInvokeOpenSearchMLCommonsRole) that needs permission to call your domain.
Select Map and confirm the user or role shows up under Mapped users.Figure 5: Set permissions in OpenSearch dashboards security plugin
Return back to the CloudFormation stack console, check the box, ‘I acknowledge that AWS CloudFormation might create IAM resources with customised names‘ and click on ‘Create Stack’.
After the stack is deployed, it will create the Amazon Bedrock-ML connector (ConnectorId) and a model identifier (ModelId). Figure 6: CloudFormation stack outputs
Copy the ModelId from the Outputs tab of the CloudFormation stack starting with prefix ‘OpenSearch-bedrock-mm-’ from your CloudFormation console. You will be using this ModelId in the further steps.
Step 2: Create the OpenSearch ingest pipeline with the text_image_embedding processor
You can create an ingest pipeline with the text_image_embedding processor, which transforms the images and descriptions into embeddings during the indexing process.
In the following request payload, you provide the following parameters to the text_image_embedding processor. Specify which index fields to convert to embeddings, which field should store the vector embeddings, and which ML model to use to perform the vector conversion.
model_id (<model_id>) – The model identifier from the previous step.
Embedding (<vector_embedding>) – The k-NN field that stores the vector embeddings.
field_map (<product_description> and <image_binary>) – The field name of the product description and the product image in binary format.
Step 4: Create the k-NN index and ingest the retail dataset
Create the k-NN index and set the pipeline created in the previous step as the default pipeline. Set index.knn to True to perform an approximate k-NN search. The vector_embedding field type must be mapped as a knn_vector. vector_embedding field dimension must be mapped with the number of dimensions of the vector that the model provides.
Amazon Titan Multimodal Embeddings G1 lets you choose the size of the output vector (either 256, 512, or 1024). In this post, you will be using the default 1024 dimensional vectors from the model. You can check the size of dimensions of the model by selecting ‘Providers’ -> ‘Amazon’ tab -> ‘Titan Multimodal Embeddings G1’ tab -> ‘Model attributes’, from your Bedrock console.
Given the smaller size of the dataset and to bias for better recall, you use the faiss engine with the hnsw algorithm and the default l2 space type for your k-NN index. For more information about different engines and space types, refer to k-NN index.
Finally, you ingest the retail dataset into the k-NN index using a bulk request. For the ingestion code, refer to the step 7, ‘Ingest the dataset into k-NN index using Bulk request‘ in the Jupyter notebook.
Step 5: Perform multimodal search experiments
Perform the following experiments to explore multimodal search and compare results. For text search, use the sample query “Trendy footwear for women” and set the number of results to 5 (size) throughout the experiments.
Experiment 1: Lexical search
This experiment shows you the limitations of simple lexical search and how the results can be improved using multimodal search.
Run a match query against the product_description field by using the following example query payload:
As shown in the preceding figure, the first three results refer to a jacket, glasses, and scarf, which are irrelevant to the query. These were returned because of the matching keywords between the query, “Trendy footwear for women” and the product descriptions, such as “trendy” and “women.” Only the last two results are relevant to the query because they contain footwear items.
Only the last two products fulfil the intent of the query, which was to find products that match all words in the query.
Experiment 2: Multimodal search with only text as input
In this experiment, you will use the Titan Multimodal Embeddings model that you deployed previously and run a neural search with only “Trendy footwear for women” (text) as input.
In the k-NN vector field (vector_embedding) of the neural query, you pass the model_id, query_text, and k value as shown in the following example. k denotes the number of results returned by the k-NN search.
Figure 8: Results from multimodal search using text
Observation:
As shown in the preceding figure, all five results are relevant because each represents a style of footwear. Additionally, the gender preference from the query (women) is also matched in all the results, which indicates that the Titan multimodal embeddings preserved the gender context in both the query and nearest document vectors.
Experiment 3: Multimodal search with only an image as input
In this experiment, you will use only a product image as the input query.
You will use the same neural query and parameters as in the previous experiment but pass the query_image parameter instead of using the query_text parameter. You need to convert the image into binary format and pass the binary string to the query_image parameter:
Figure 9: Image of a woman’s sandal used as the query input
Figure 10: Results from multimodal search using an image
Observation:
As shown in the preceding figure, by passing an image of a woman’s sandal, you were able to retrieve similar footwear styles. Though this experiment provides a different set of results compared to the previous experiment, all the results are highly related to the search query. All the matching documents are similar to the searched product image, not only in terms of the product category (footwear) but also in terms of the style (summer footwear), color, and gender affinity of the product.
Experiment 4: Multimodal search with both text and an image
In this last experiment, you will run the same neural query but pass both the image of a woman’s sandal and the text, “dark color” as inputs.
Figure 11: Image of a woman’s sandal used as part of the query input
As before, you will convert the image into its binary form before passing it to the query:
ML-powered search with OpenSearch and set up you multimodal search solution in your own environment using the guidelines in this post. The solution code is also available on the GitHub repo.
About the Authors
Praveen Mohan Prasad is an Analytics Specialist Technical Account Manager at Amazon Web Services and helps customers with pro-active operational reviews on analytics workloads. Praveen actively researches on applying machine learning to improve search relevance.
Hajer Bouafif is an Analytics Specialist Solutions Architect at Amazon Web Services. She focuses on Amazon OpenSearch Service and helps customers design and build well-architected analytics workloads in diverse industries. Hajer enjoys spending time outdoors and discovering new cultures.
Aruna Govindaraju is an Amazon OpenSearch Specialist Solutions Architect and has worked with many commercial and open-source search engines. She is passionate about search, relevancy, and user experience. Her expertise with correlating end-user signals with search engine behavior has helped many customers improve their search experience. Her favourite pastime is hiking the New England trails and mountains.
AWS Glue is a fully managed, serverless data integration service provided by Amazon Web Services (AWS) that uses Apache Spark as one of its backend processing engines (as of this writing, you can use Python Shell, Spark, or Ray).
Data skew occurs when the data being processed is not evenly distributed across the Spark cluster, causing some tasks to take significantly longer to complete than others. This can lead to inefficient resource utilization, longer processing times, and ultimately, slower performance. Data skew can arise from various factors, including uneven data distribution, skewed join keys, or uneven data processing patterns. Even though the biggest issue is often having nodes running out of disk during shuffling, which leads to nodes falling like dominoes and job failures, it’s also important to mention that data skew is hidden. The stealthy nature of data skew means it can often go undetected because monitoring tools might not flag an uneven distribution as a critical issue, and logs don’t always make it evident. As a result, a developer may observe that their AWS Glue jobs are completing without apparent errors, yet the system could be operating far from its optimal efficiency. This hidden inefficiency not only increases operational costs due to longer runtimes but can also lead to unpredictable performance issues that are difficult to diagnose without a deep dive into the data distribution and task run patterns.
For example, in a dataset of customer transactions, if one customer has significantly more transactions than the others, it can cause a skew in the data distribution.
Identifying and handling data skew issues is key to having good performance on Apache Spark and therefore on AWS Glue jobs that use Spark as a backend. In this post, we show how you can identify data skew and discuss the different techniques to mitigate data skew.
How to detect data skew
When an AWS Glue job has issues with local disks (split disk issues), doesn’t scale with the number of workers, or has low CPU usage (you can enable Amazon CloudWatch metrics for your job to be able to see this), you may have a data skew issue. You can detect data skew with data analysis or by using the Spark UI. In this section, we discuss how to use the Spark UI.
The Spark UI provides a comprehensive view of Spark applications, including the number of tasks, stages, and their duration. To use it you need to enable Spark UI event logs for your job runs. It is enabled by default on Glue console and once enabled, Spark event log files will be created during the job run and stored in your S3 bucket. Then, those logs are parsed, and you can use the AWS Glue serverless Spark UI to visualize them. You can refer to this blogpost for more details. In those jobs where the AWS Glue serverless Spark UI does not work as it has a limit of 512 MB of logs, you can set up the Spark UI using an EC2 instance.
You can use the Spark UI to identify which tasks are taking longer to complete than others, and if the data distribution among partitions is balanced or not (remember that in Spark, one partition is mapped to one task). If there is data skew, you will see that some partitions have significantly more data than others. The following figure shows an example of this. We can see that one task is taking a lot more time than the others, which can indicate data skew.
Another thing that you can use is the summary metrics for each stage. The following screenshot shows another example of data skew.
These metrics represent the task-related metrics below which a certain percentage of tasks completed. For example, the 75th percentile task duration indicates that 75% of tasks completed in less time than this value. When the tasks are evenly distributed, you will see similar numbers in all the percentiles. When there is data skew, you will see very biased values in each percentile. In the preceding example, it didn’t write many shuffle files (less than 50 MiB) in Min, 25th percentile, Median, and 75th percentile. However, in Max, it wrote 460 MiB, 10 times the 75th percentile. It means there was at least one task (or up to 25% of tasks) that wrote much bigger shuffle files than the rest of the tasks. You can also see that the duration of the tax in Max is 46 seconds and the Median is 2 seconds. These are all indicators that your dataset may have data skew.
AWS Glue interactive sessions
You can use interactive sessions to load your data from the AWS Glue Data Catalog or just use Spark methods to load the files such as Parquet or CSV that you want to analyze. You can use a similar script to the following to detect data skew from the partition size perspective; the more important issue is related to data skew while shuffling, and this script does not detect that kind of skew:
from pyspark.sql.functions import spark_partition_id, asc, desc
#input_dataframe being the dataframe where you want to check for data skew
partition_sizes_df=input_dataframe\
    .withColumn("partitionId", spark_partition_id())\
    .groupBy("partitionId")\
    .count()\
    .orderBy(asc("count"))\
    .withColumnRenamed("count","partition_size")
#calculate average and standar deviation for the partition sizes
avg_size = partition_sizes_df.agg({"partition_size": "avg"}).collect()[0][0]
std_dev_size = partition_sizes_df.agg({"partition_size": "stddev"}).collect()[0][0]

"""
 the code calculates the absolute difference between each value in the "partition_size" column and the calculated average (avg_size).
 then, calculates twice the standard deviation (std_dev_size) and use
 that as a boolean mask where the condition checks if the absolute difference is greater than twice the standard deviation
 in order to mark a partition 'skewed'
"""
skewed_partitions_df = partition_sizes_df.filter(abs(partition_sizes_df["partition_size"] - avg_size) > 2 * std_dev_size)
if skewed_partitions_df.count() > 0:
    skewed_partitions = [row["partition_id"] for row in skewed_partitions_df.collect()]
    print(f"The following partitions have significantly different sizes: {skewed_partitions}")
else:
    print("No data skew detected.")
You can calculate the average and standard deviation of partition sizes using the agg() function and identify partitions with significantly different sizes using the filter() function, and you can print their indexes if any skewed partitions are detected. Otherwise, the output prints that no data skew is detected.
This code assumes that your data is structured, and you may need to modify it if your data is of a different type.
How to handle data skew
You can use different techniques in AWS Glue to handle data skew; there is no single universal solution. The first thing to do is confirm that you’re using latest AWS Glue version, for example AWS Glue 4.0 based on Spark 3.3 has enabled by default some configs like Adaptative Query Execution (AQE) that can help improve performance when data skew is present.
The following are some of the techniques that you can employ to handle data skew:
Filter and perform – If you know which keys are causing the skew, you can filter them out, perform your operations on the non-skewed data, and then handle the skewed keys separately.
Implementing incremental aggregation – If you are performing a large aggregation operation, you can break it up into smaller stages because in large datasets, a single aggregation operation (like sum, average, or count) can be resource-intensive. In those cases, you can perform intermediate actions. This could involve filtering, grouping, or additional aggregations. This can help distribute the workload across the nodes and reduce the size of intermediate data.
Using a custom partitioner – If your data has a specific structure or distribution, you can create a custom partitioner that partitions your data based on its characteristics. This can help make sure that data with similar characteristics is in the same partition and reduce the size of the largest partition.
Using broadcast join – If your dataset is small but exceeds the spark.sql.autoBroadcastJoinThreshold value (default is 10 MB), you have the option to either provide a hint to use broadcast join or adjust the threshold value to accommodate your dataset. This can be an effective strategy to optimize join operations and mitigate data skew issues resulting from shuffling large amounts of data across nodes.
Salting – This involves adding a random prefix to the key of skewed data. By doing this, you distribute the data more evenly across the partitions. After processing, you can remove the prefix to get the original key values.
These are just a few techniques to handle data skew in PySpark; the best approach will depend on the characteristics of your data and the operations you are performing.
The following is an example of joining skewed data with the salting technique:
from pyspark.sql import SparkSession
from pyspark.sql.functions import lit, ceil, rand, concat, col

# Define the number of salt values
num_salts = 3

# Function to identify skewed keys
def identify_skewed_keys(df, key_column, threshold):
    key_counts = df.groupBy(key_column).count()
    return key_counts.filter(key_counts['count'] > threshold).select(key_column)

# Identify skewed keys
skewed_keys = identify_skewed_keys(skewed_data, "key", skew_threshold)

# Splitting the dataset
skewed_data_subset = skewed_data.join(skewed_keys, ["key"], "inner")
non_skewed_data_subset = skewed_data.join(skewed_keys, ["key"], "left_anti")

# Apply salting to skewed data
skewed_data_subset = skewed_data_subset.withColumn("salt", ceil((rand() * 10) % num_salts))
skewed_data_subset = skewed_data_subset.withColumn("salted_key", concat(col("key"), lit("_"), col("salt")))

# Replicate skewed rows in non-skewed dataset
def replicate_skewed_rows(df, keys, multiplier):
    replicated_df = df.join(keys, ["key"]).crossJoin(spark.range(multiplier).withColumnRenamed("id", "salt"))
    replicated_df = replicated_df.withColumn("salted_key", concat(col("key"), lit("_"), col("salt")))
    return replicated_df.drop("salt")

replicated_non_skewed_data = replicate_skewed_rows(non_skewed_data, skewed_keys, num_salts)

# Perform the JOIN operation on the salted keys for skewed data
result_skewed = skewed_data_subset.join(replicated_non_skewed_data, "salted_key")

# Perform regular join on non-skewed data
result_non_skewed = non_skewed_data_subset.join(non_skewed_data, "key")

# Combine results
final_result = result_skewed.union(result_non_skewed)
In this code, we first define a salt value, which can be a random integer or any other value. We then add a salt column to our DataFrame using the withColumn() function, where we set the value of the salt column to a random number using the rand() function with a fixed seed. The function replicate_salt_rows is defined to replicate each row in the non-skewed dataset (non_skewed_data) num_salts times. This ensures that each key in the non-skewed data has matching salted keys. Finally, a join operation is performed on the salted_key column between the skewed and non-skewed datasets. This join is more balanced compared to a direct join on the original key, because salting and replication have mitigated the data skew.
The rand() function used in this example generates a random number between 0–1 for each row, so it’s important to use a fixed seed to achieve consistent results across different runs of the code. You can choose any fixed integer value for the seed.
The following figures illustrate the data distribution before (left) and after (right) salting. Heavily skewed key2 identified and salted into key2_0, key2_1, and key2_2, balancing the data distribution and preventing any single node from being overloaded. After processing, the results can be aggregated back, so that that the final output is consistent with the unsalted key values.
Other techniques to use on skewed data during the join operation
When you’re performing skewed joins, you can use salting or broadcasting techniques, or divide your data into skewed and regular parts before joining the regular data and broadcasting the skewed data.
If you are using Spark 3, there are automatic optimizations for trying to optimize Data Skew issues on joins. Those can be tuned because they have dedicated configs on Apache Spark.
Conclusion
This post provided details on how to detect data skew in your data integration jobs using AWS Glue and different techniques for handling it. Having a good data distribution is key to achieving the best performance on distributed processing systems like Apache Spark.
Although this post focused on AWS Glue, the same concepts apply to jobs you may be running on Amazon EMR using Apache Spark or Amazon Athena for Apache Spark.
As always, AWS welcomes your feedback. Please leave your comments and questions in the comments section.
About the Authors
Salim Tutuncu is a Sr. PSA Specialist on Data & AI, based from Amsterdam with a focus on the EMEA North and EMEA Central regions. With a rich background in the technology sector that spans roles as a Data Engineer, Data Scientist, and Machine Learning Engineer, Salim has built a formidable expertise in navigating the complex landscape of data and artificial intelligence. His current role involves working closely with partners to develop long-term, profitable businesses leveraging the AWS Platform, particularly in Data and AI use cases.
Angel Conde Manjon is a Sr. PSA Specialist on Data & AI, based in Madrid, and focuses on EMEA South and Israel. He has previously worked on research related to Data Analytics and Artificial Intelligence in diverse European research projects. In his current role, Angel helps partners develop businesses centered on Data and AI.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.
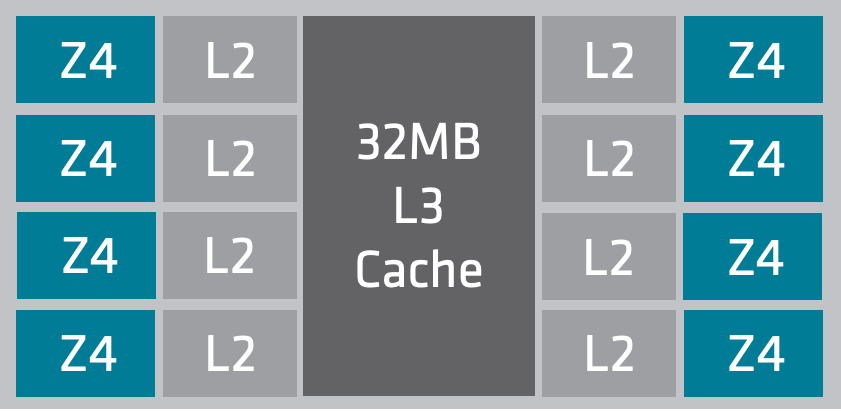
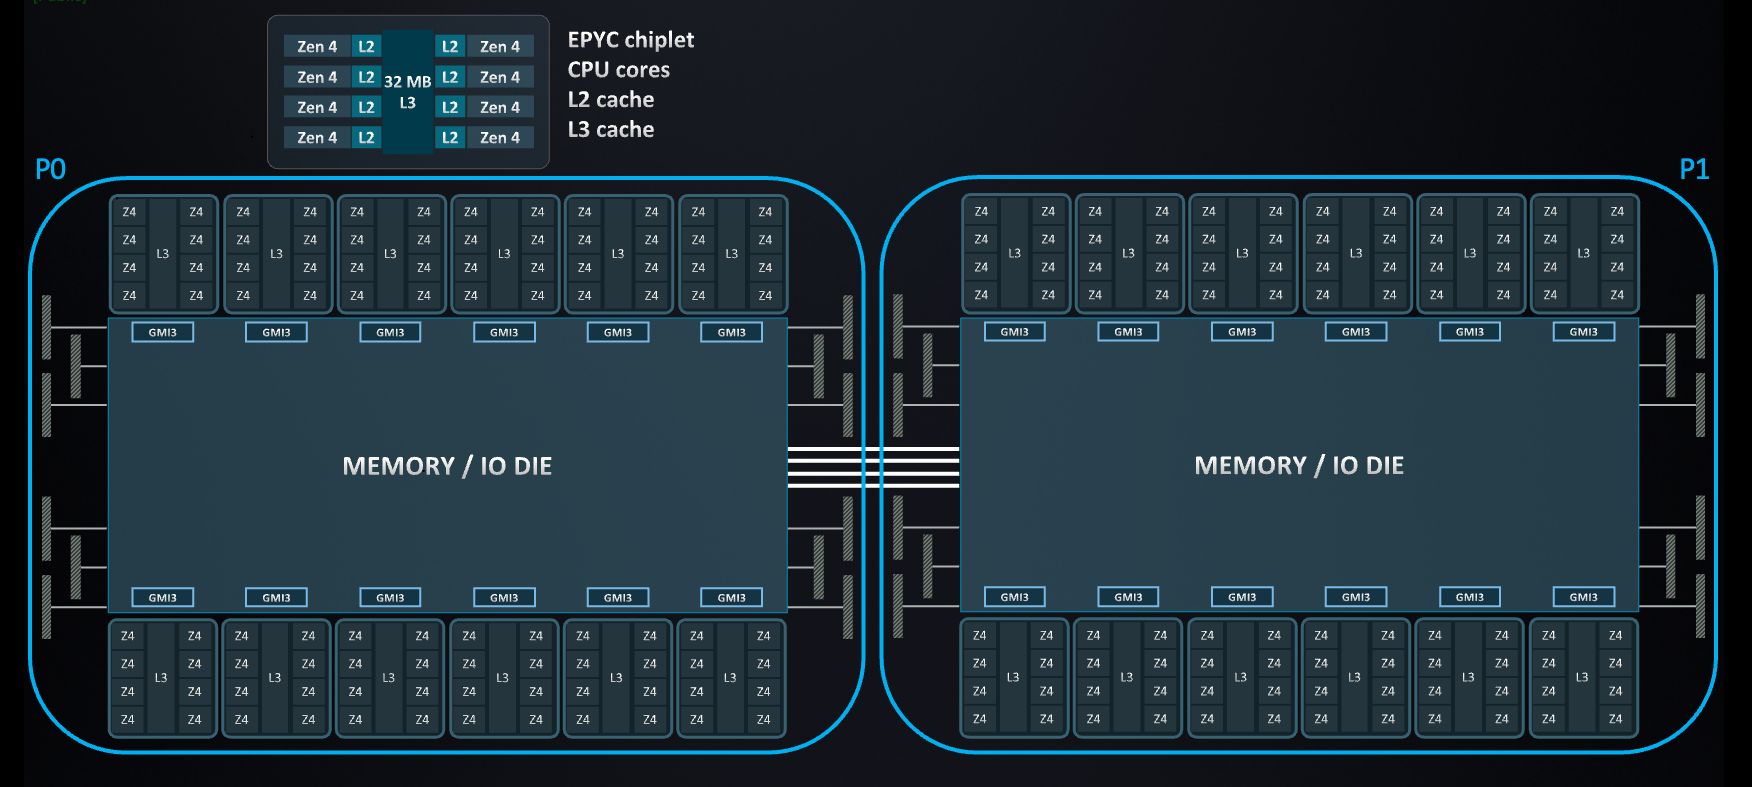
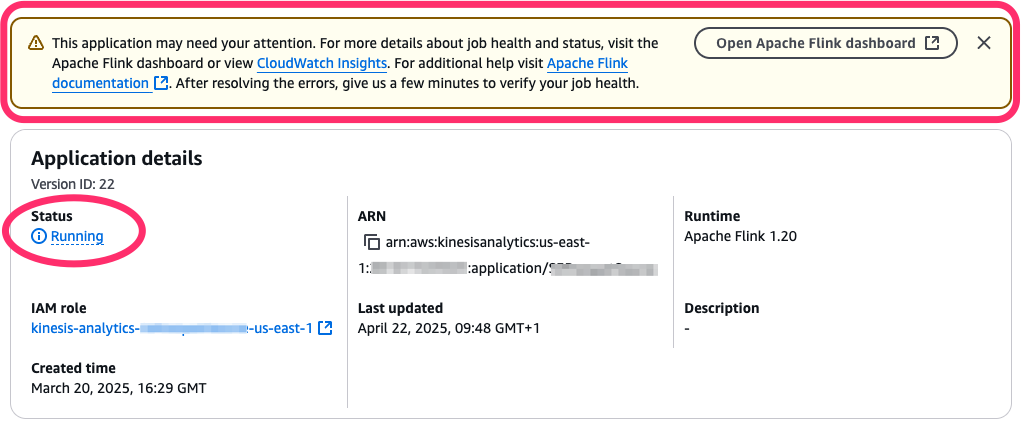
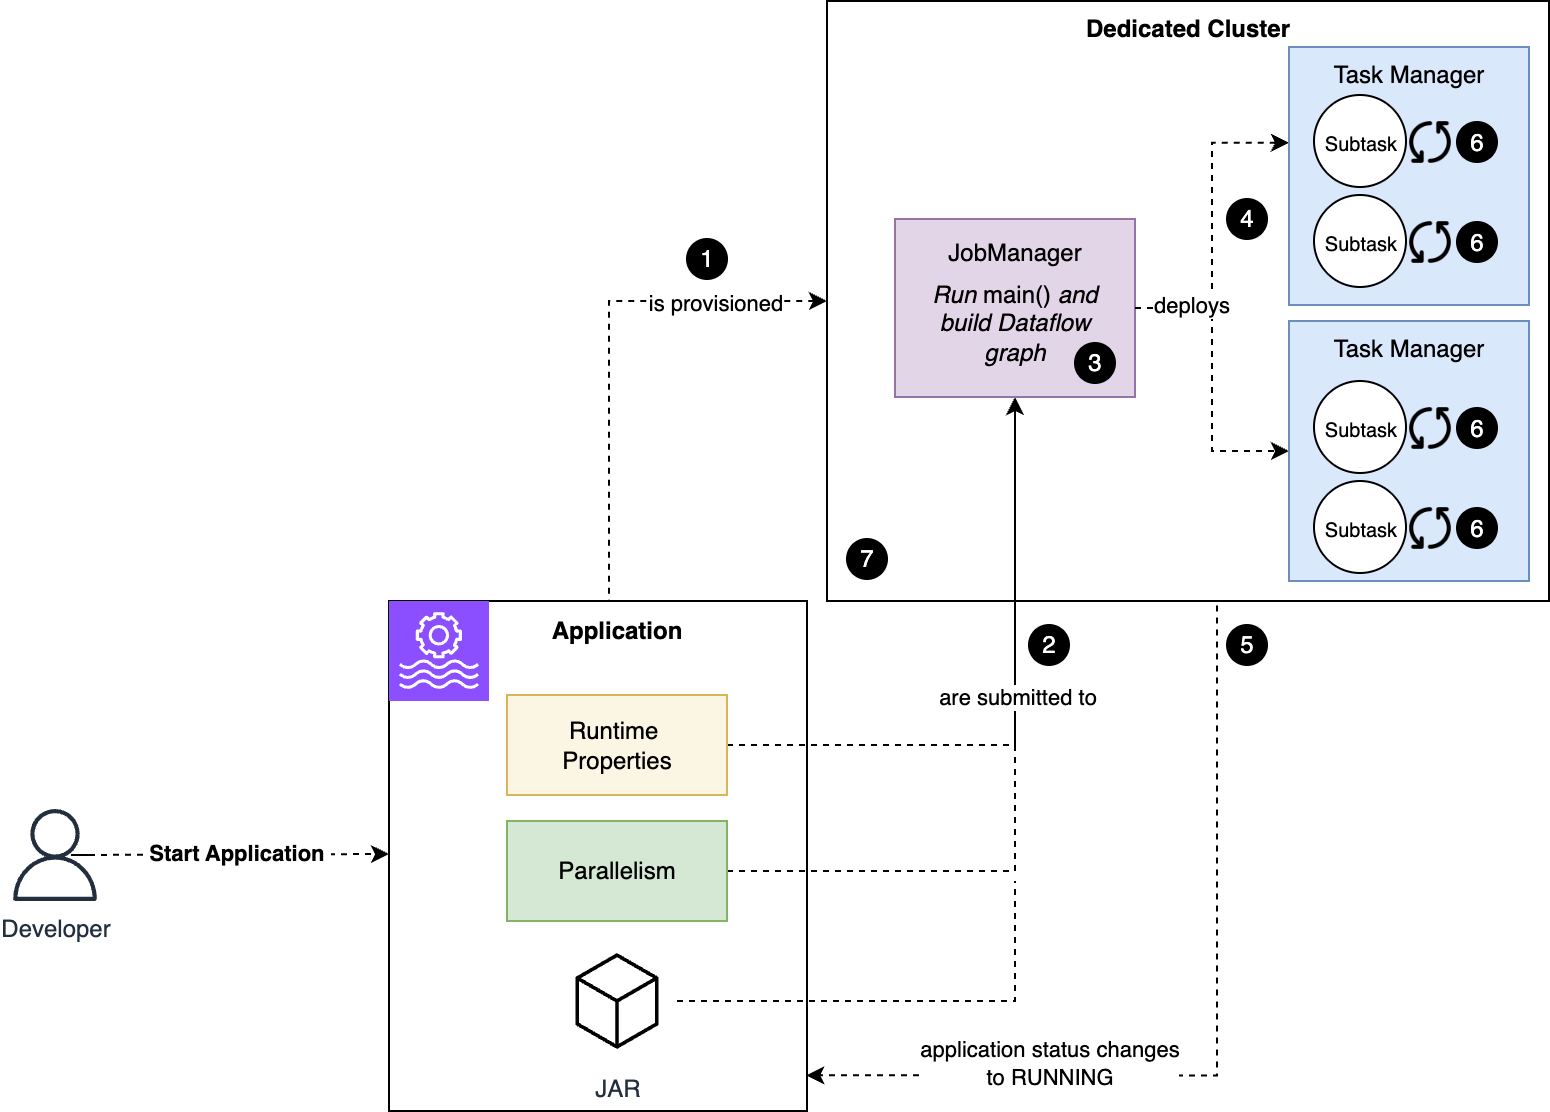
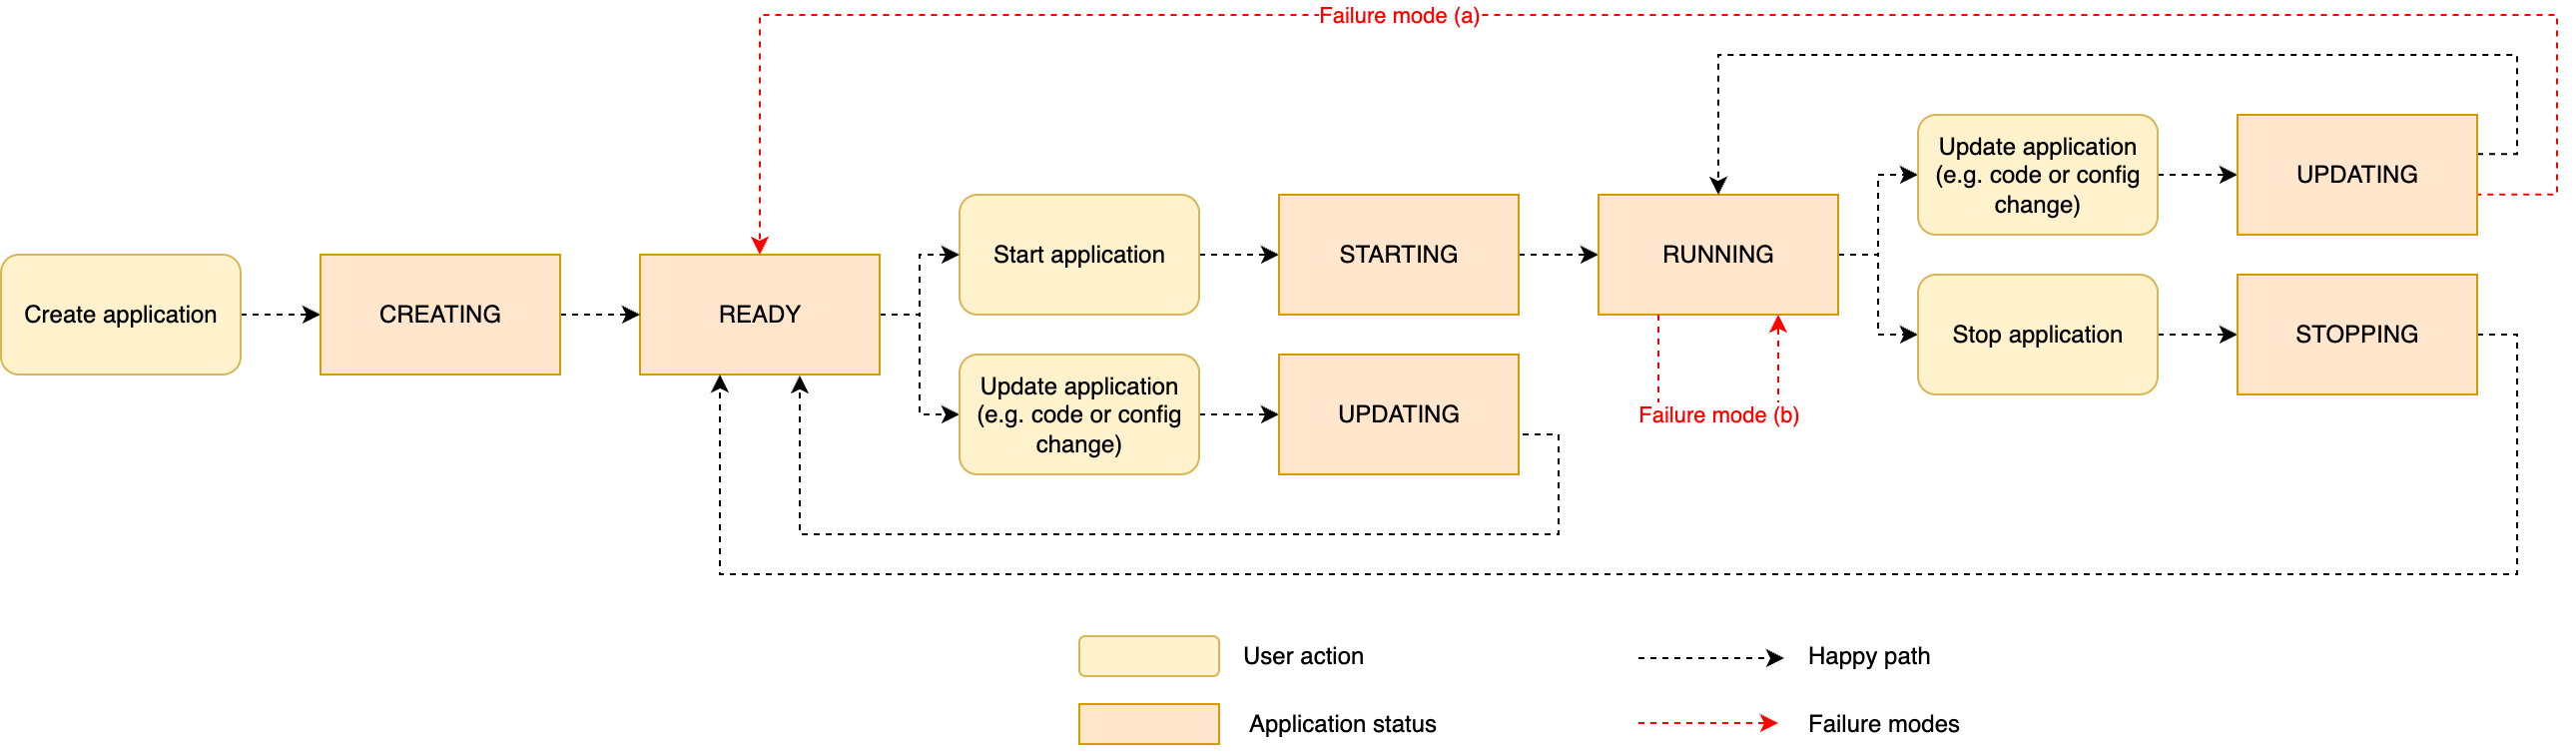
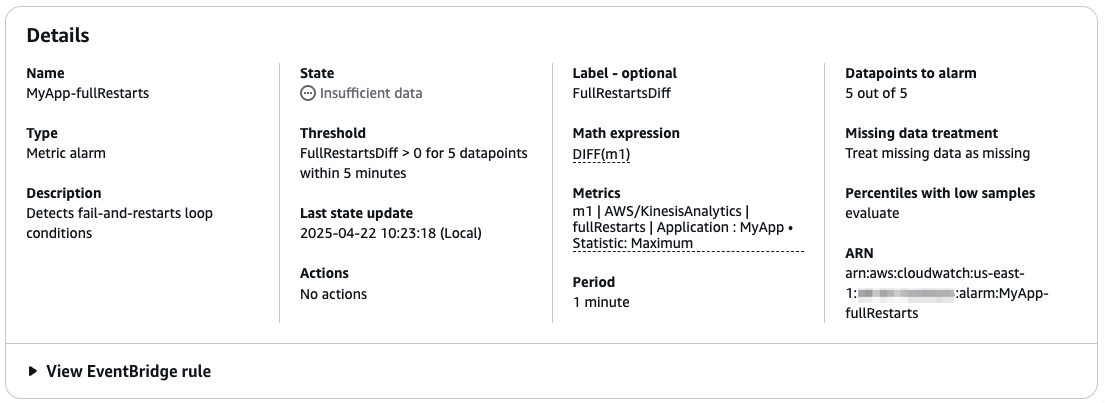
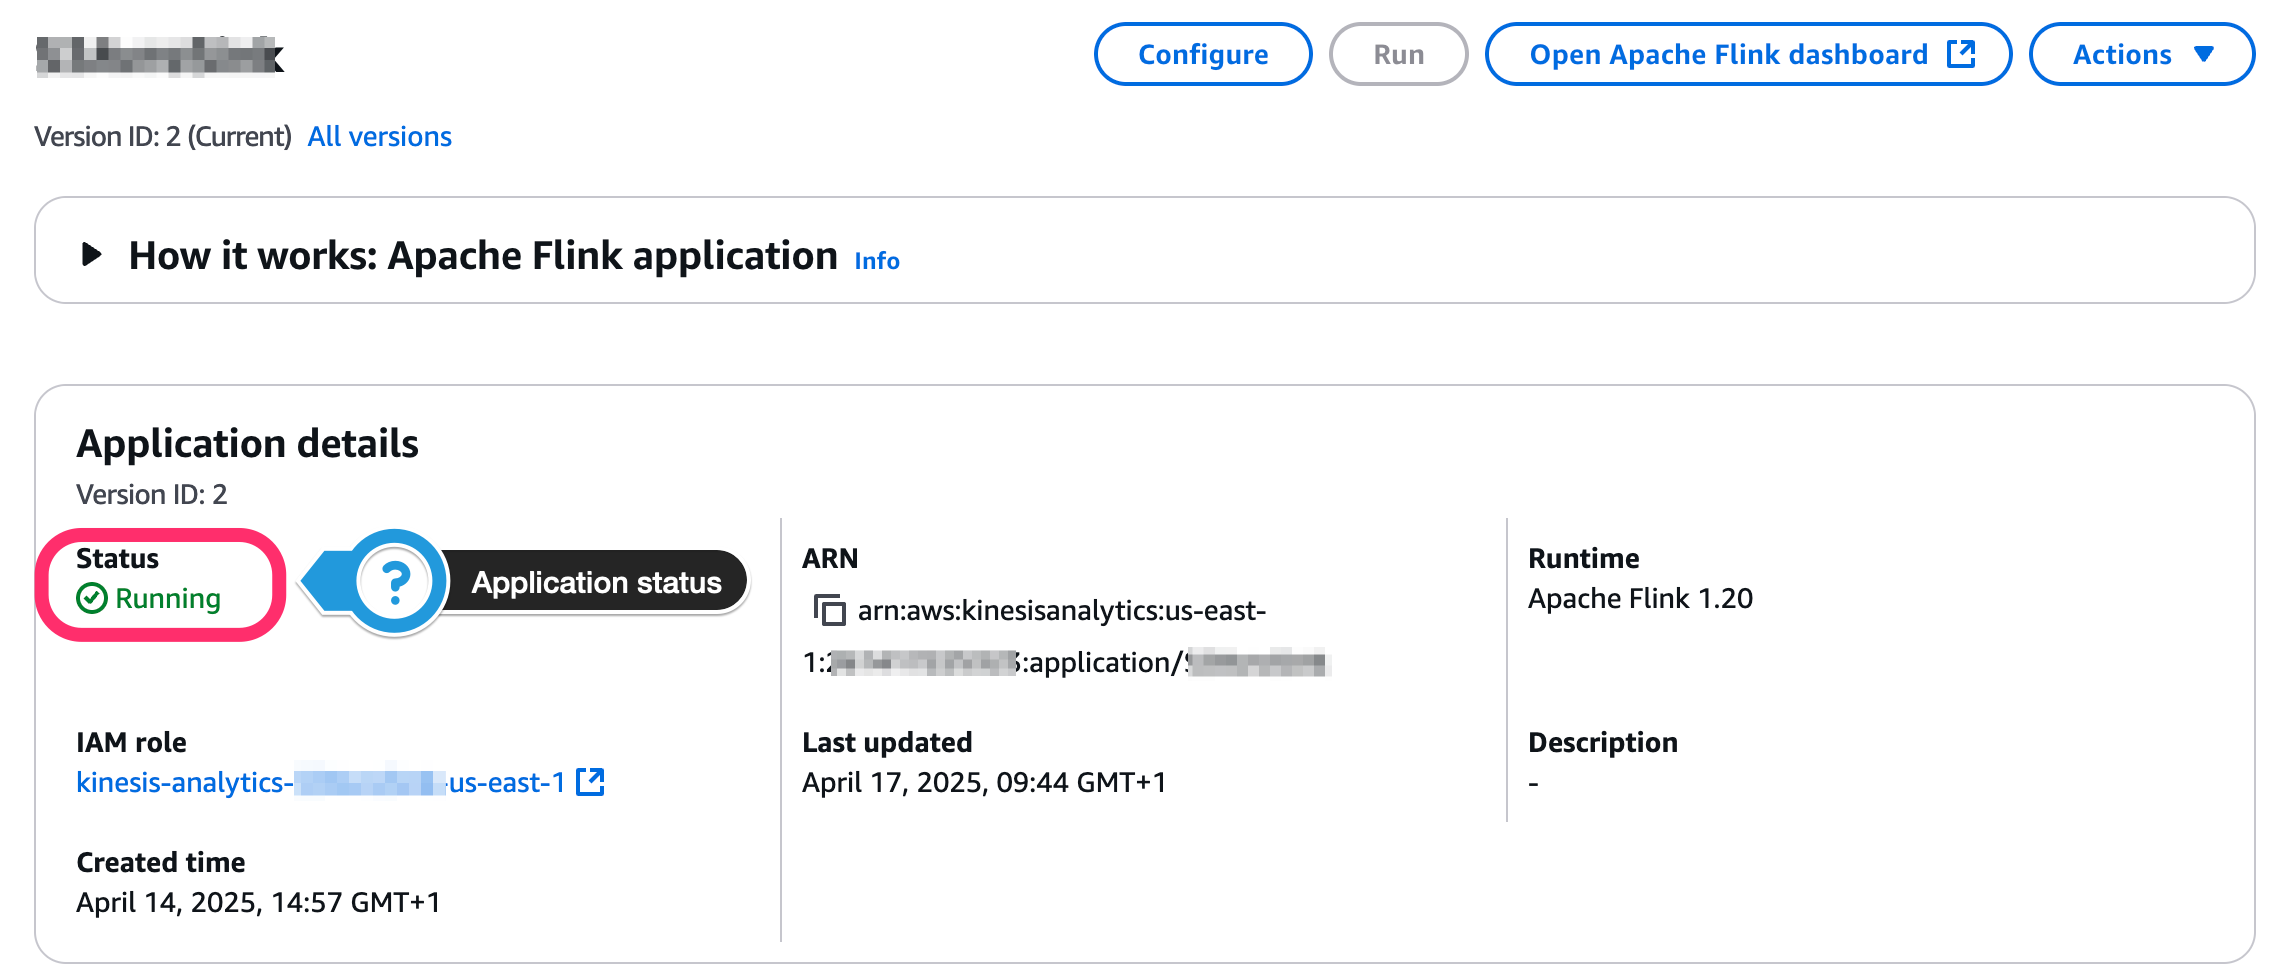
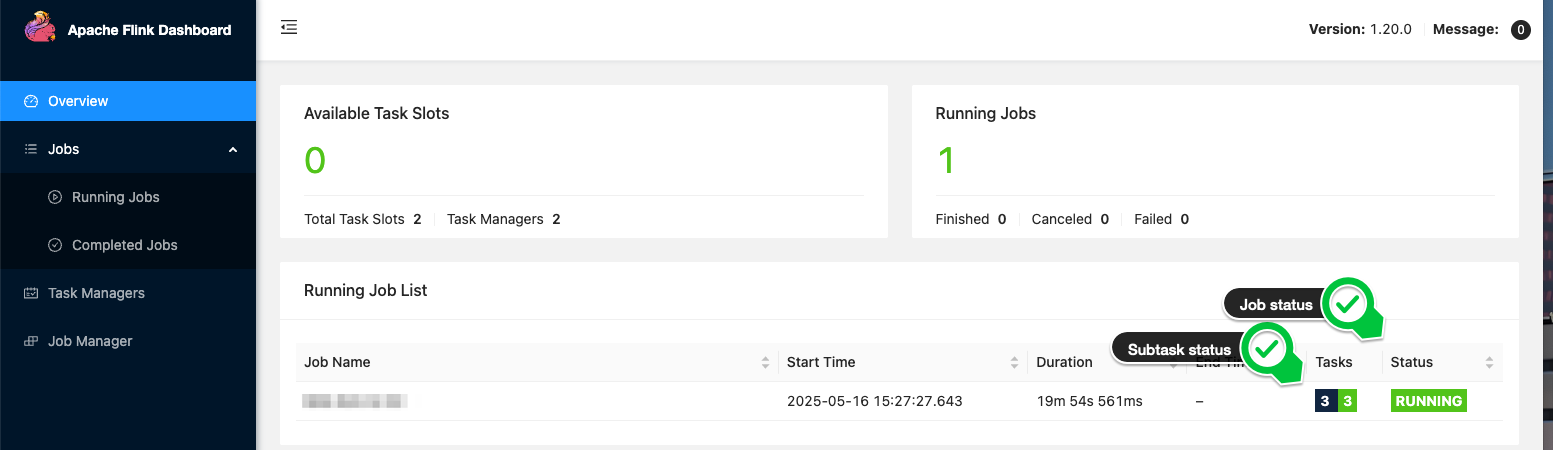
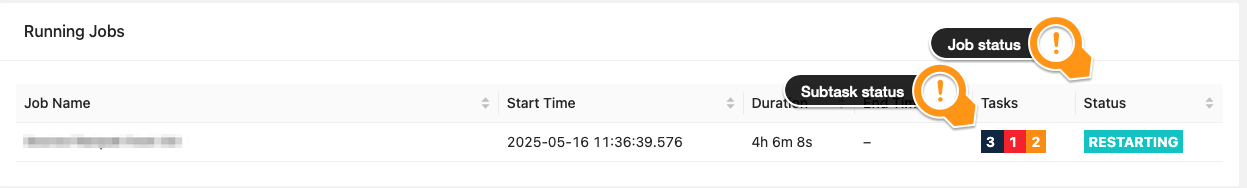
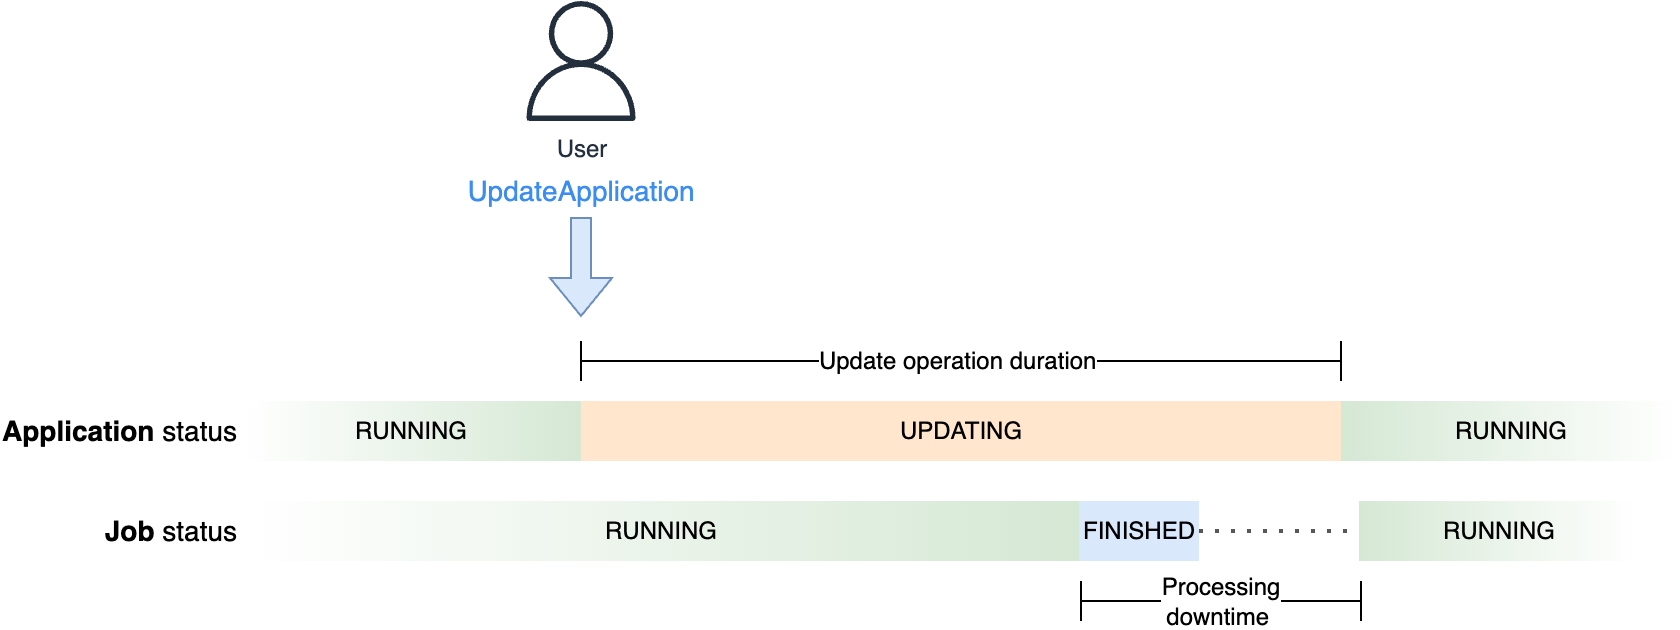
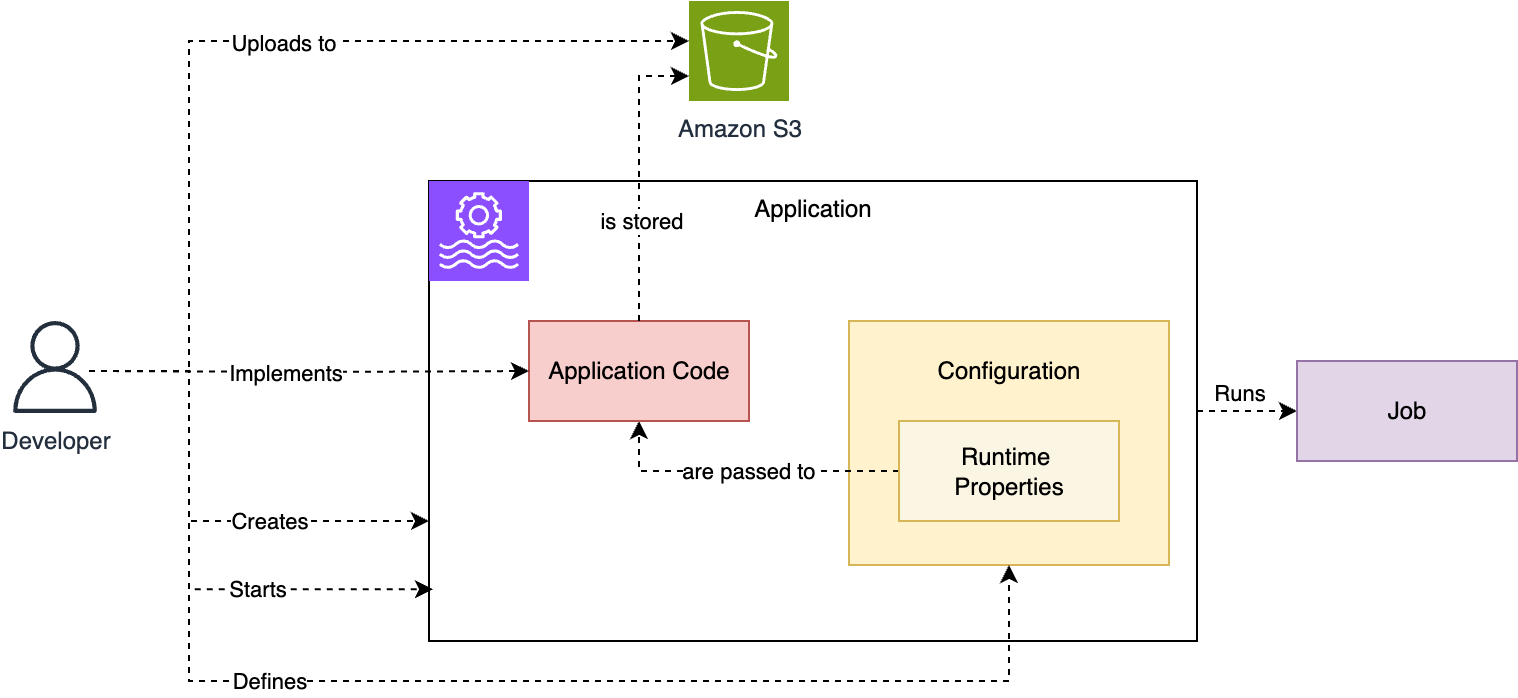
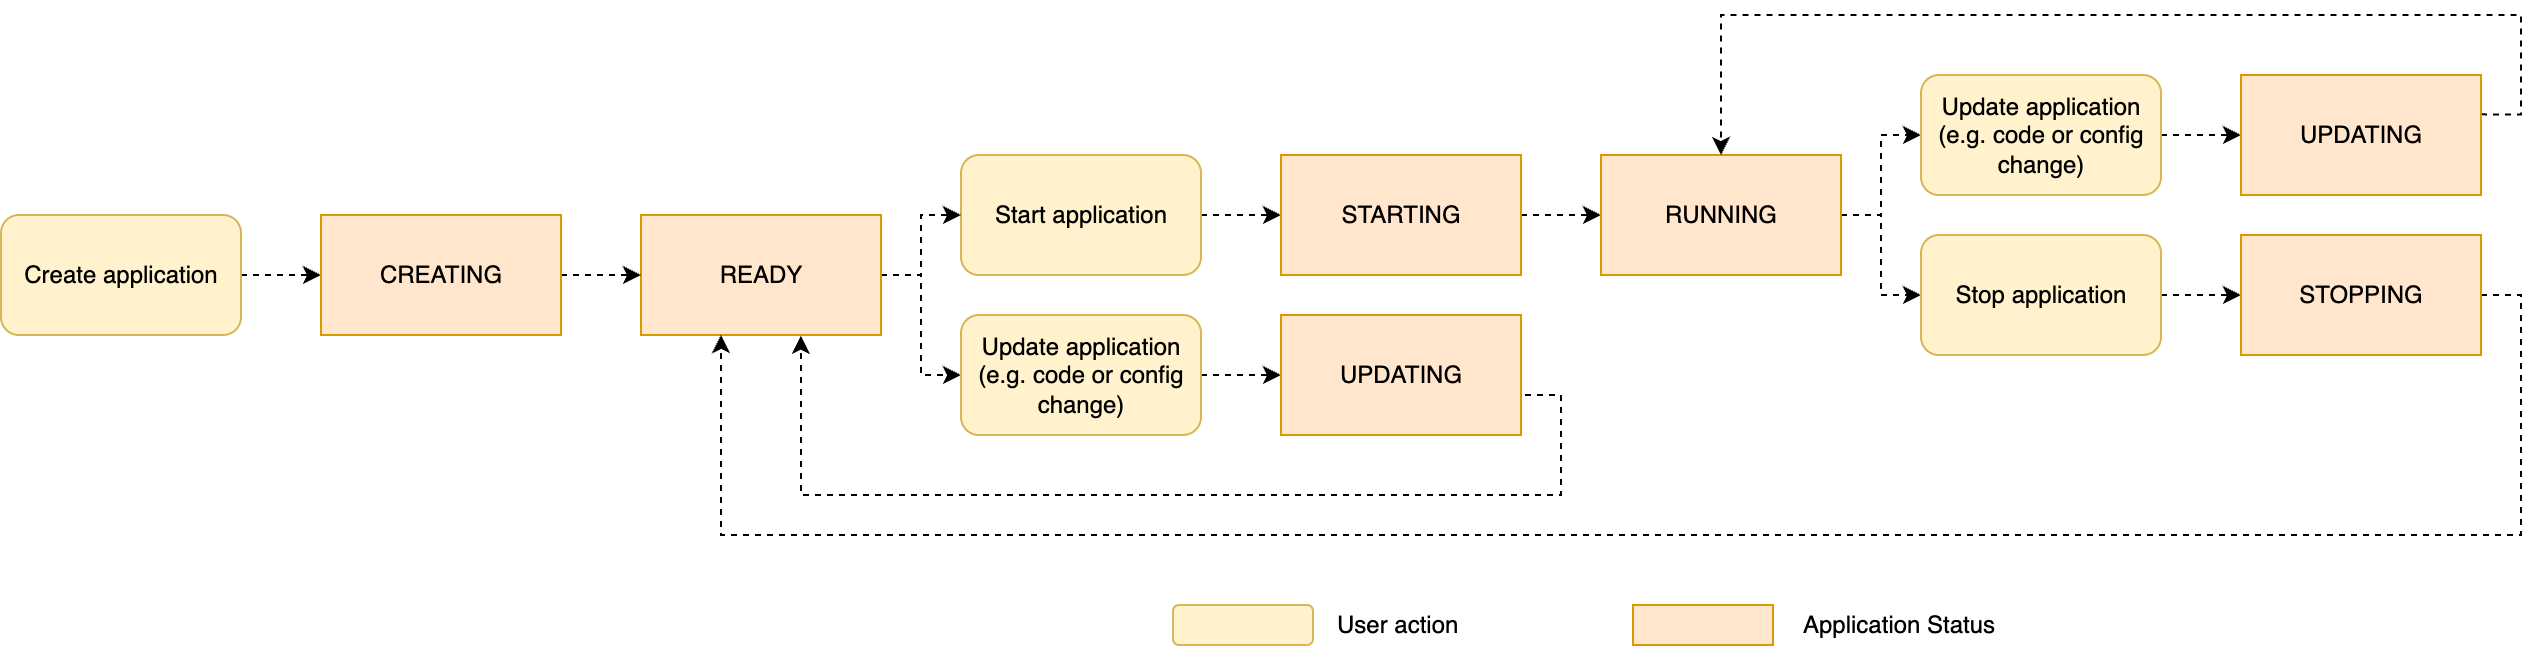
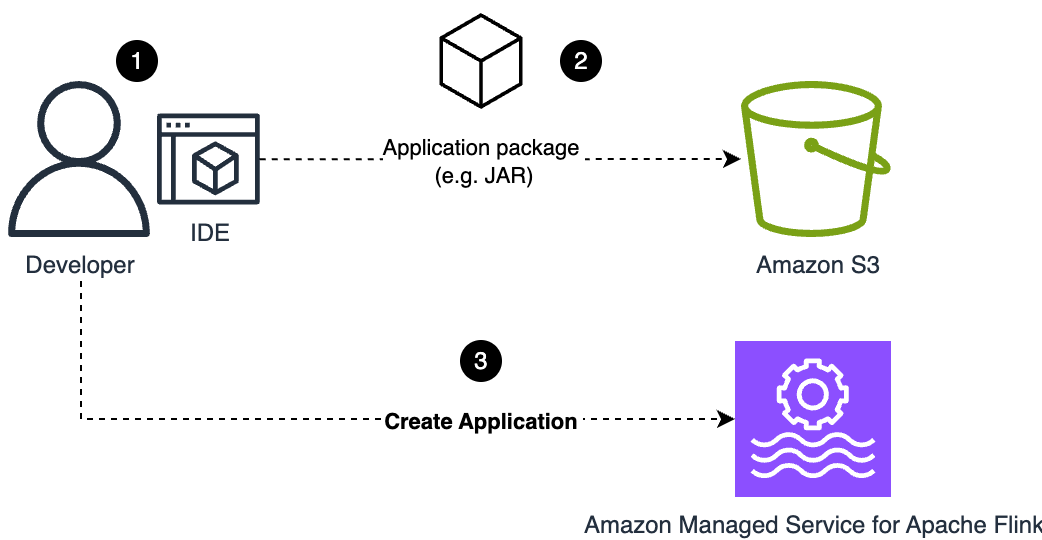
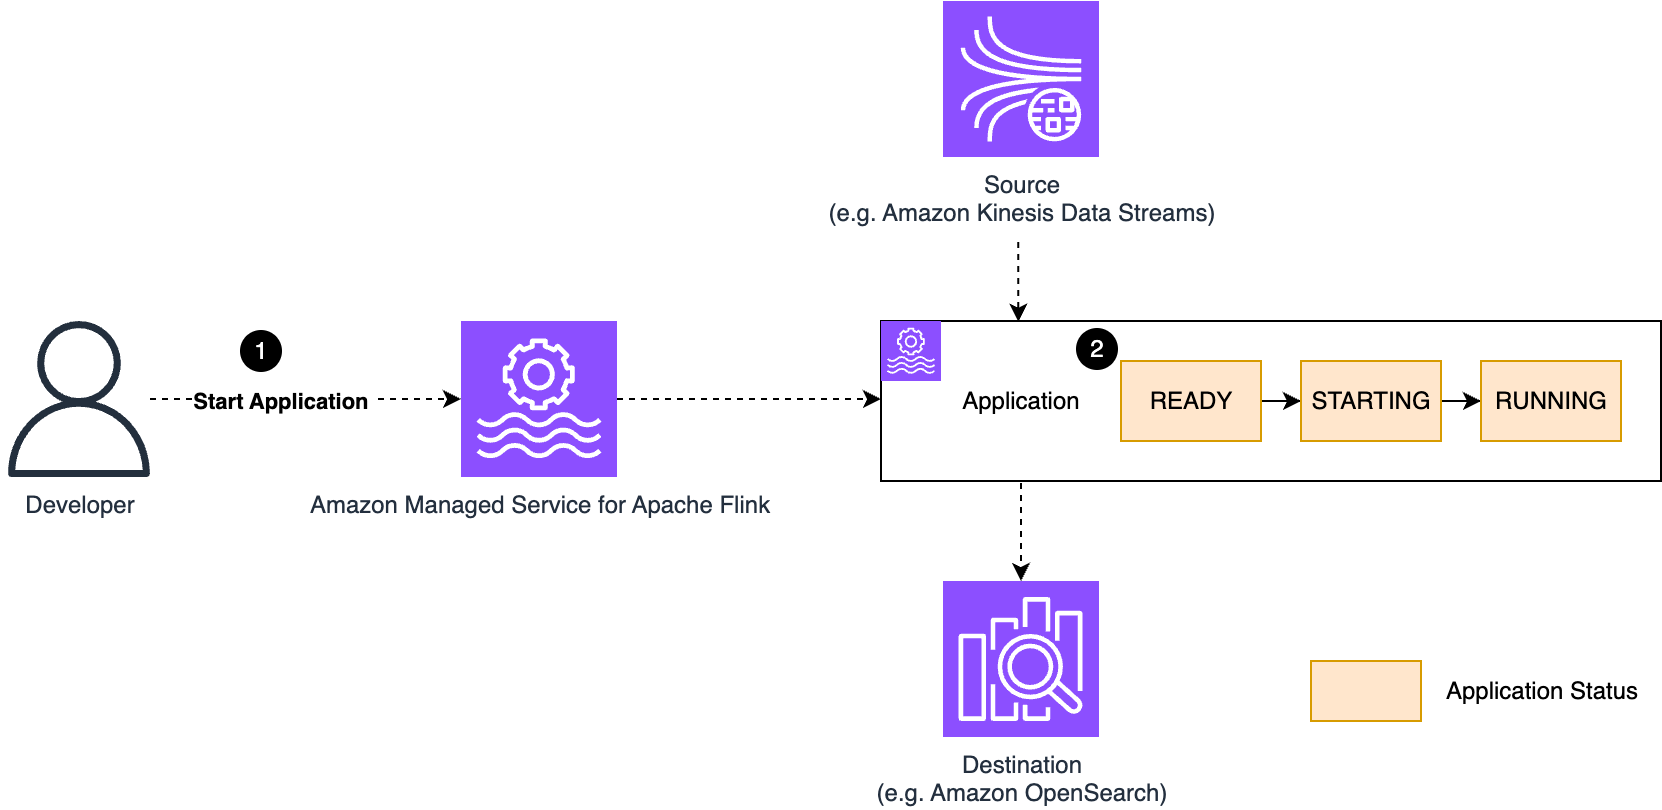
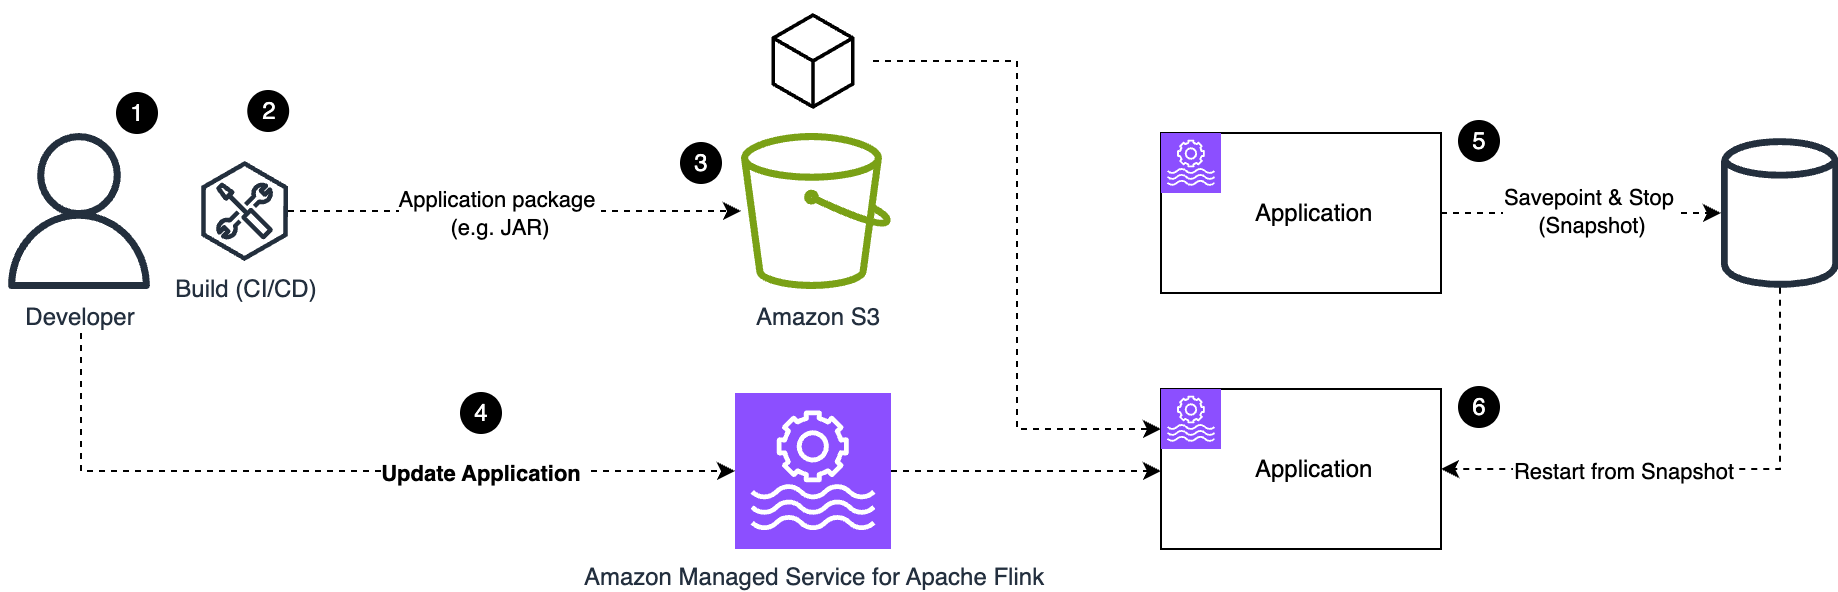
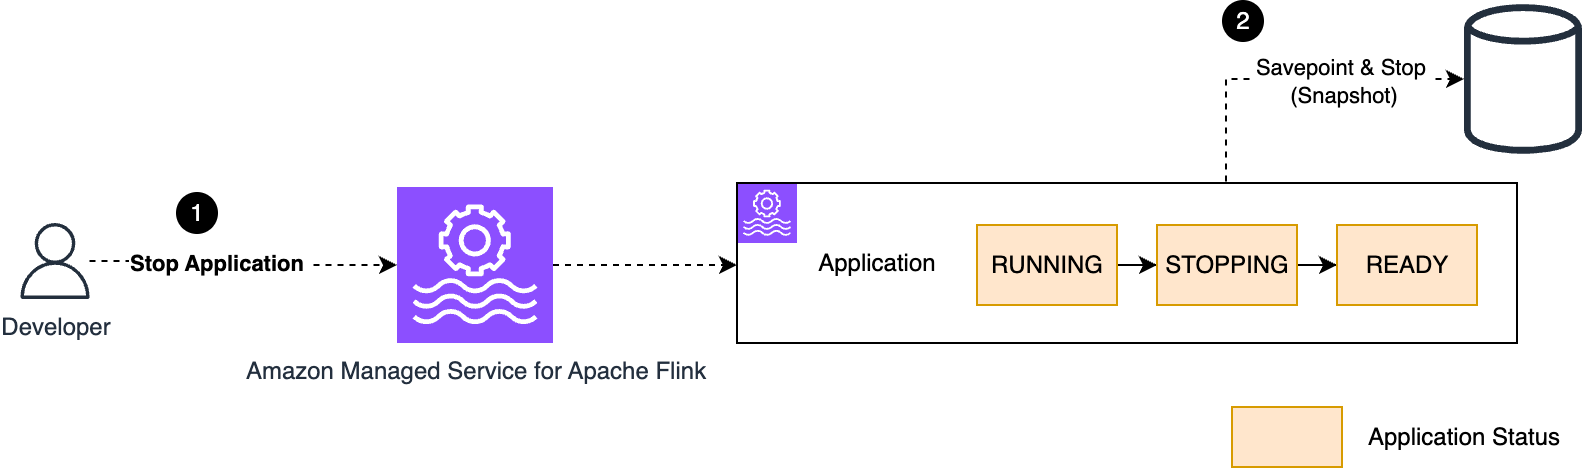
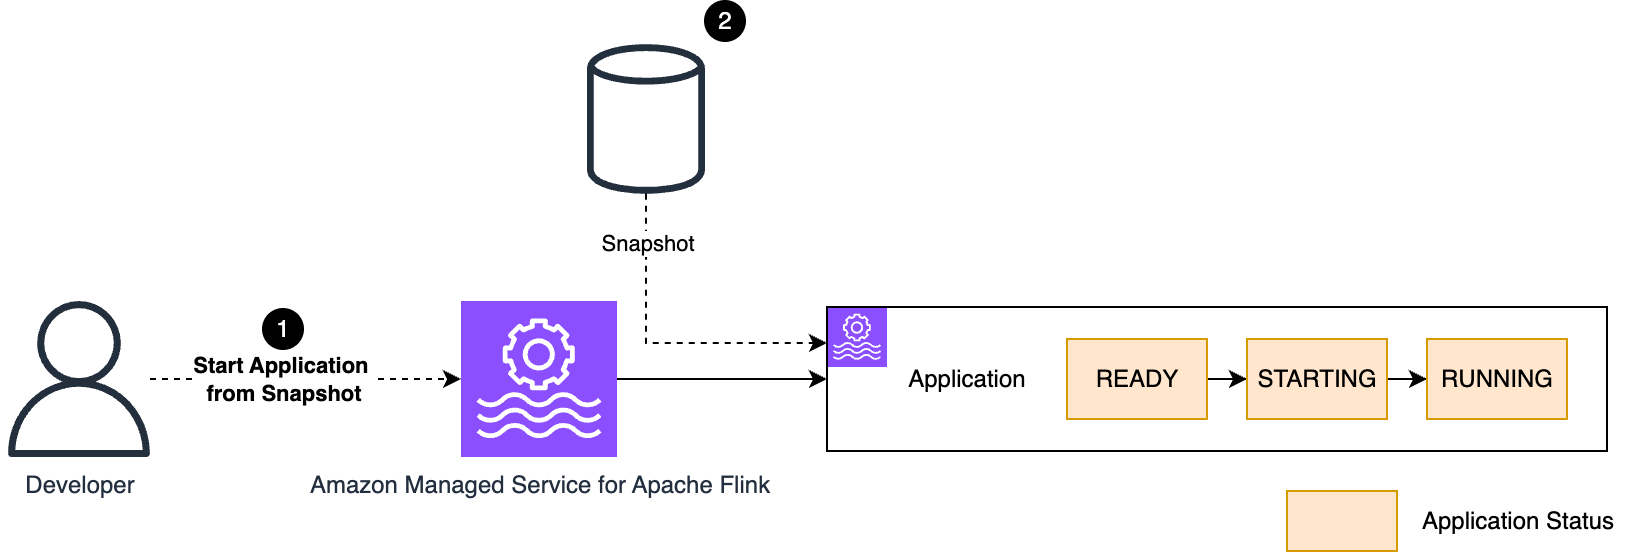
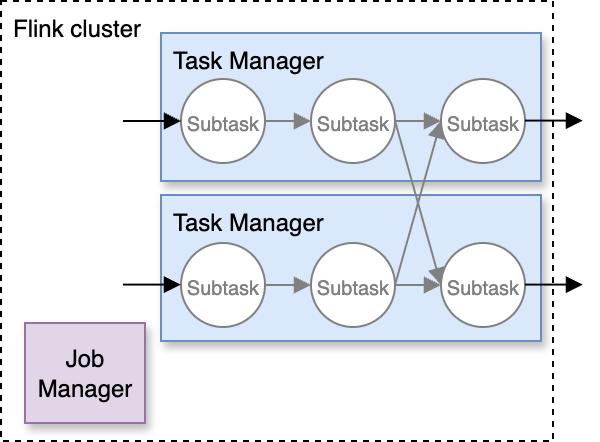
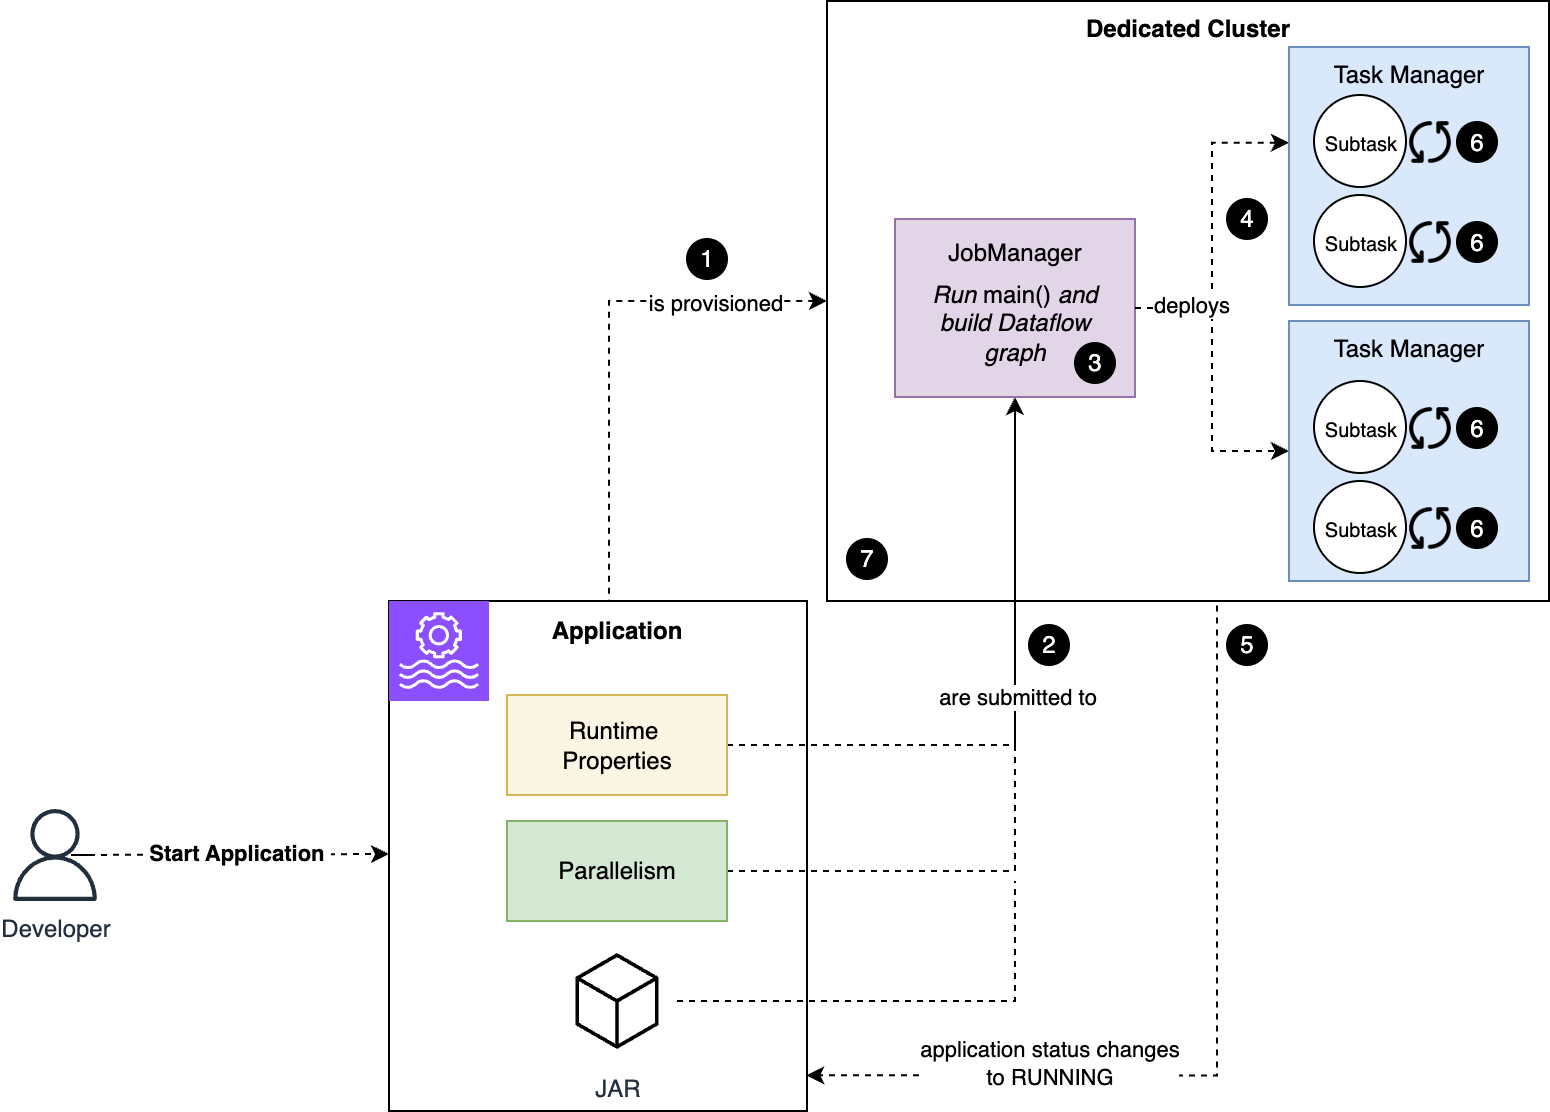
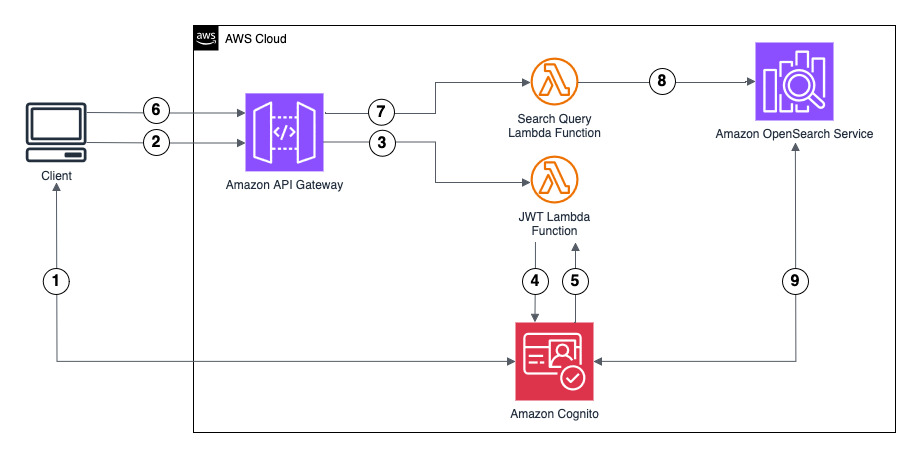
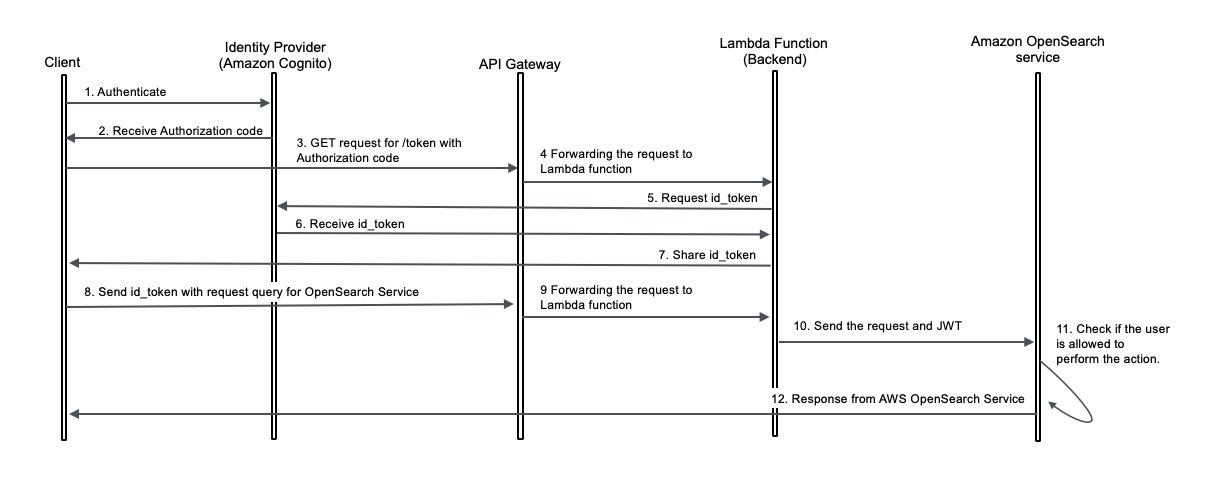

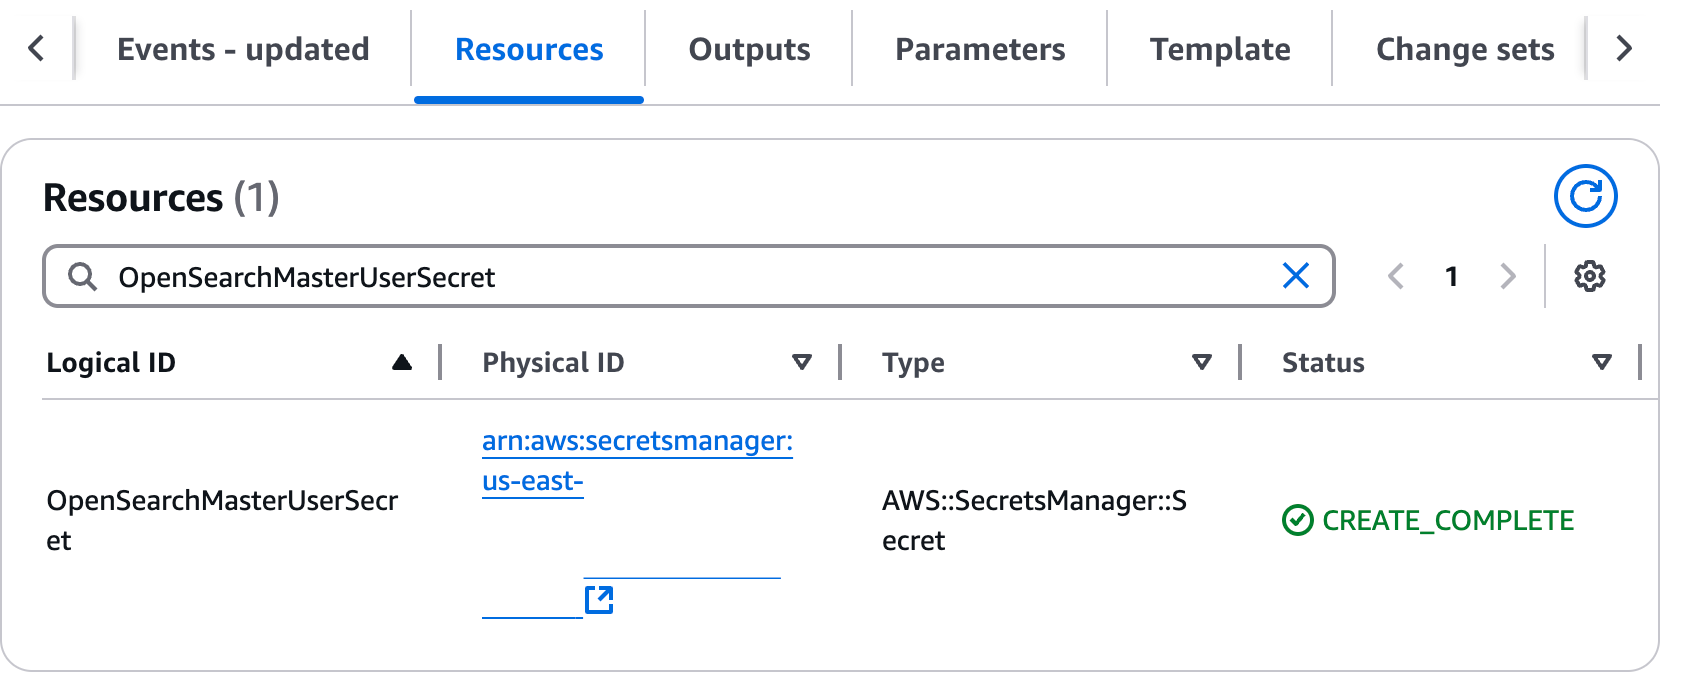
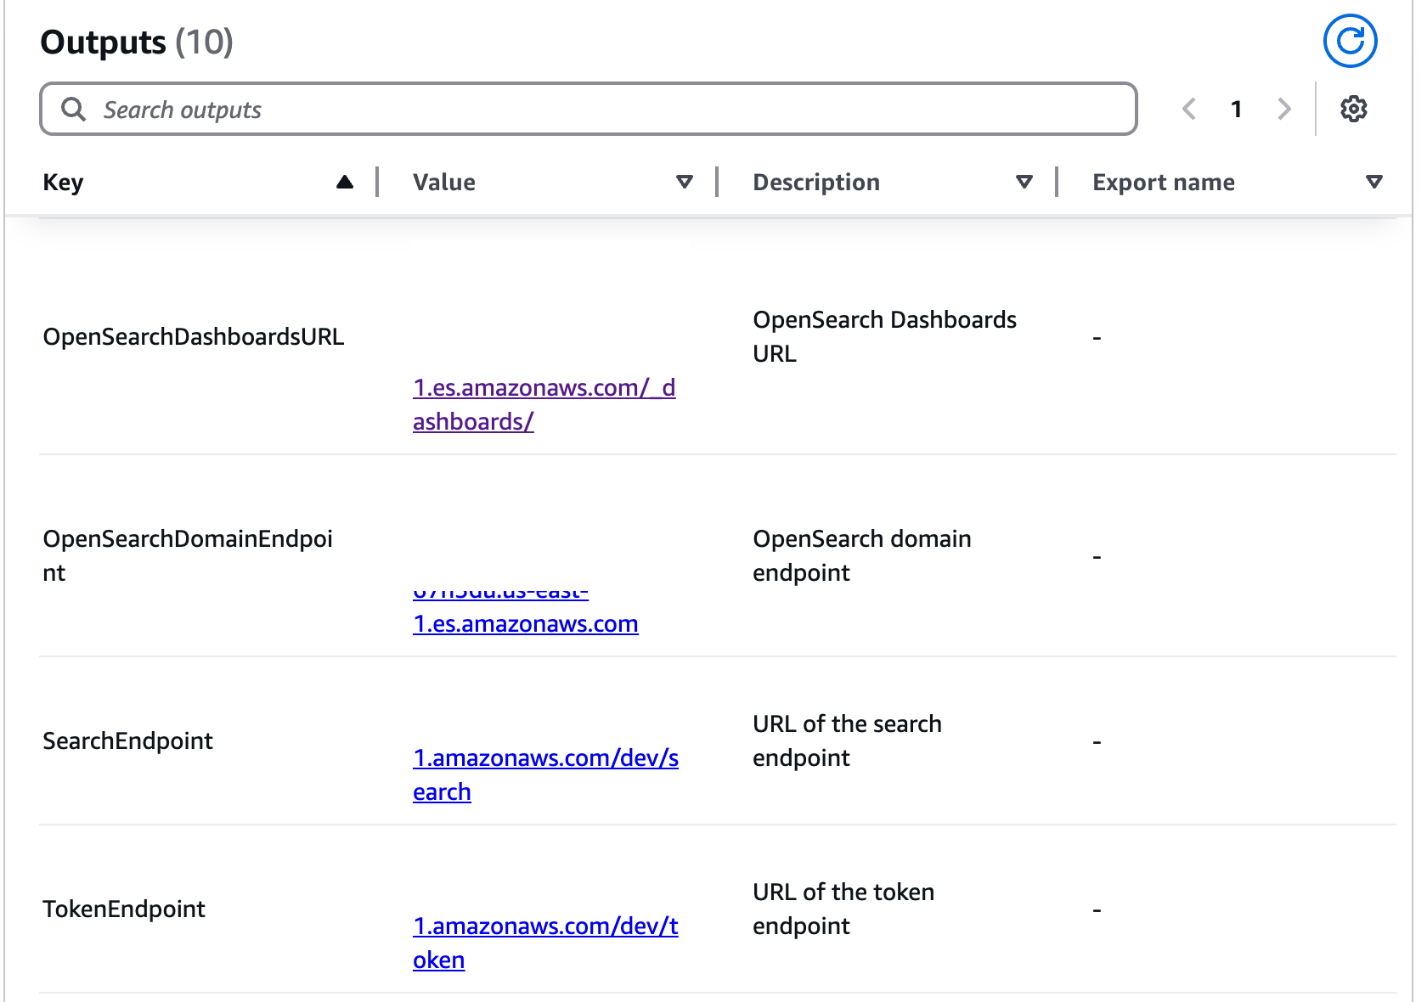
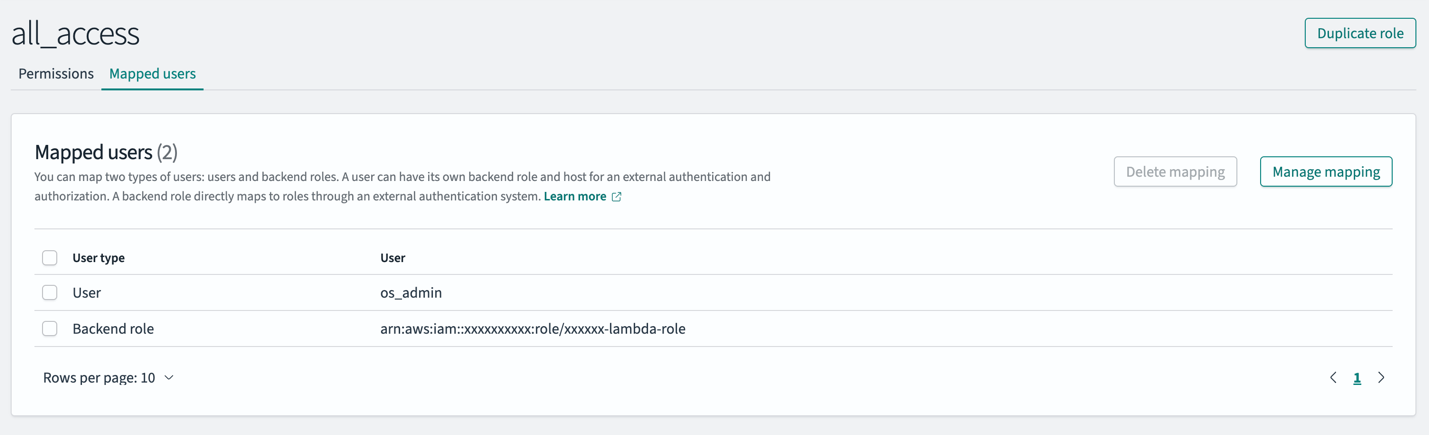
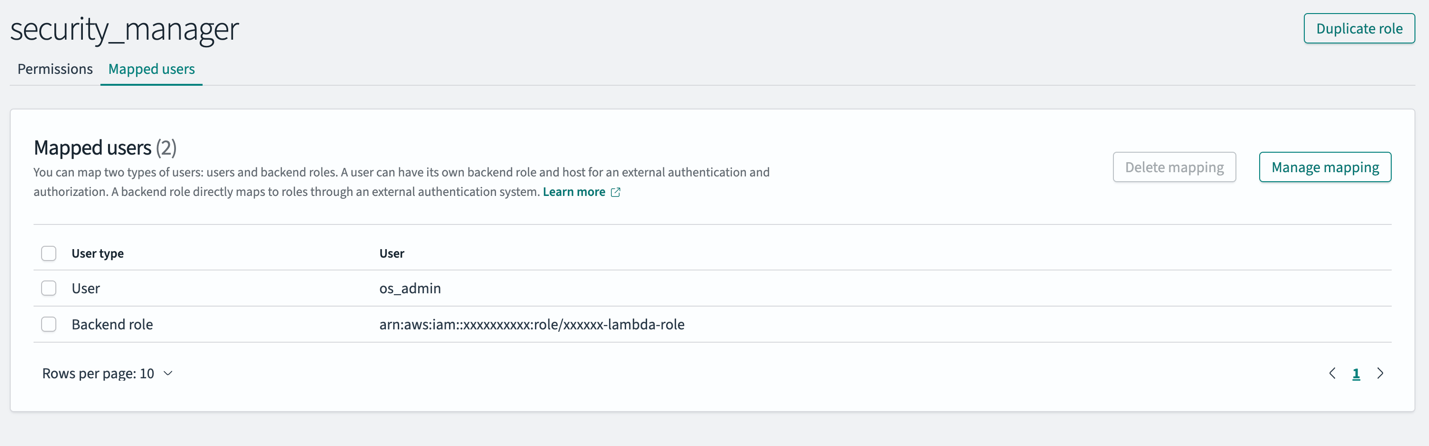
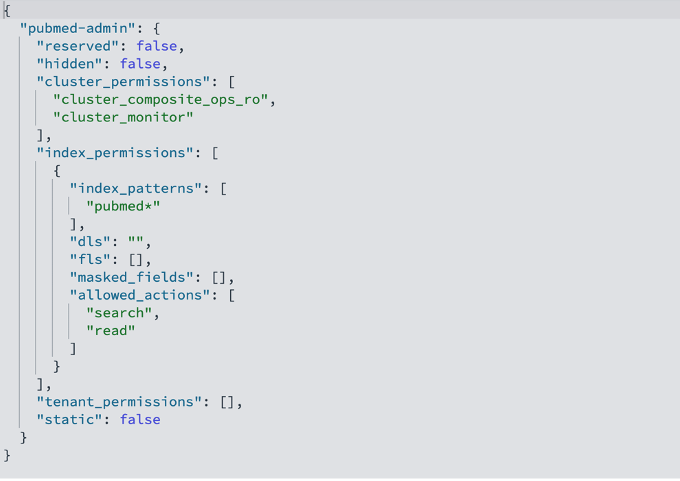
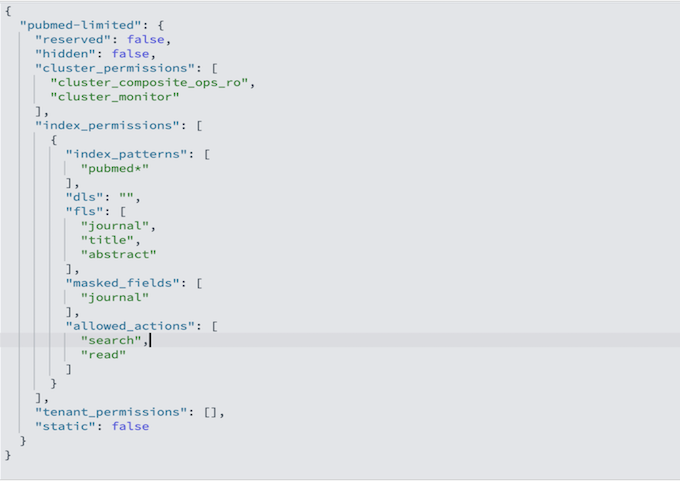
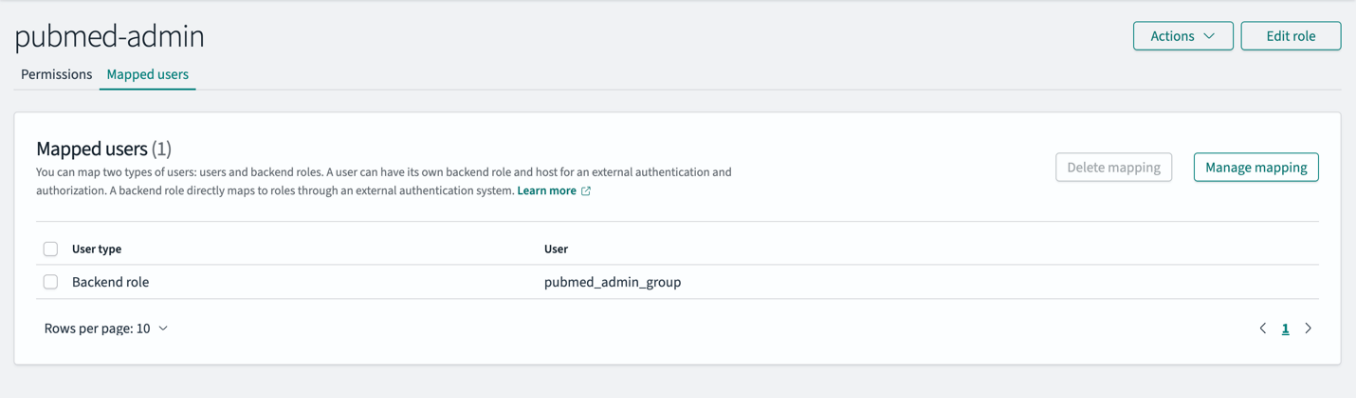
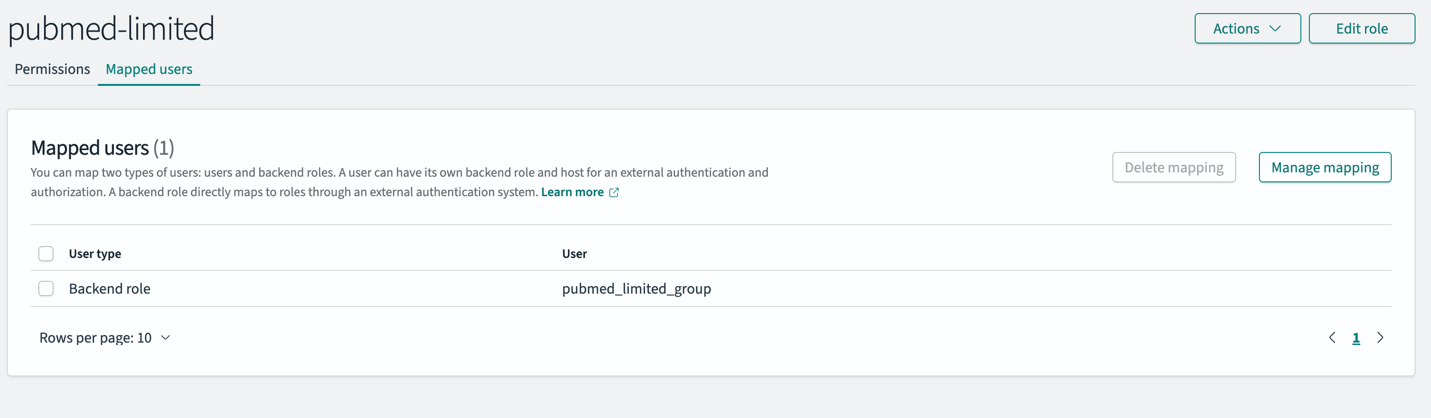
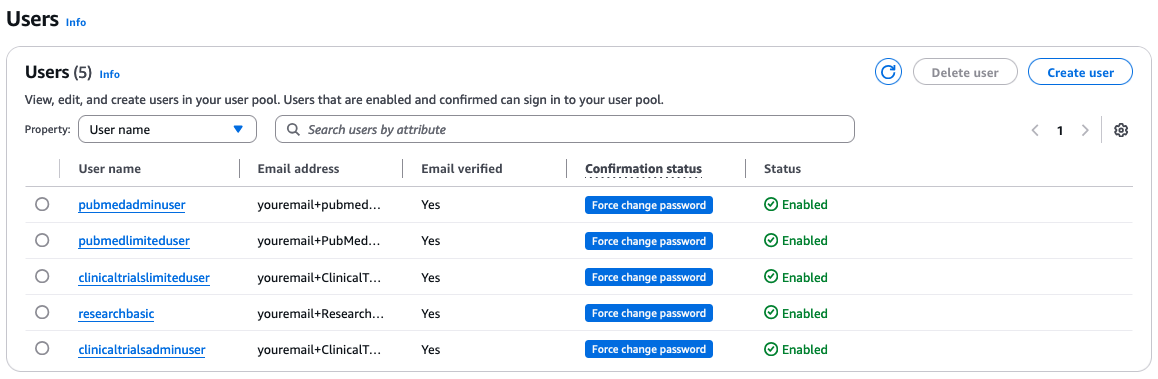
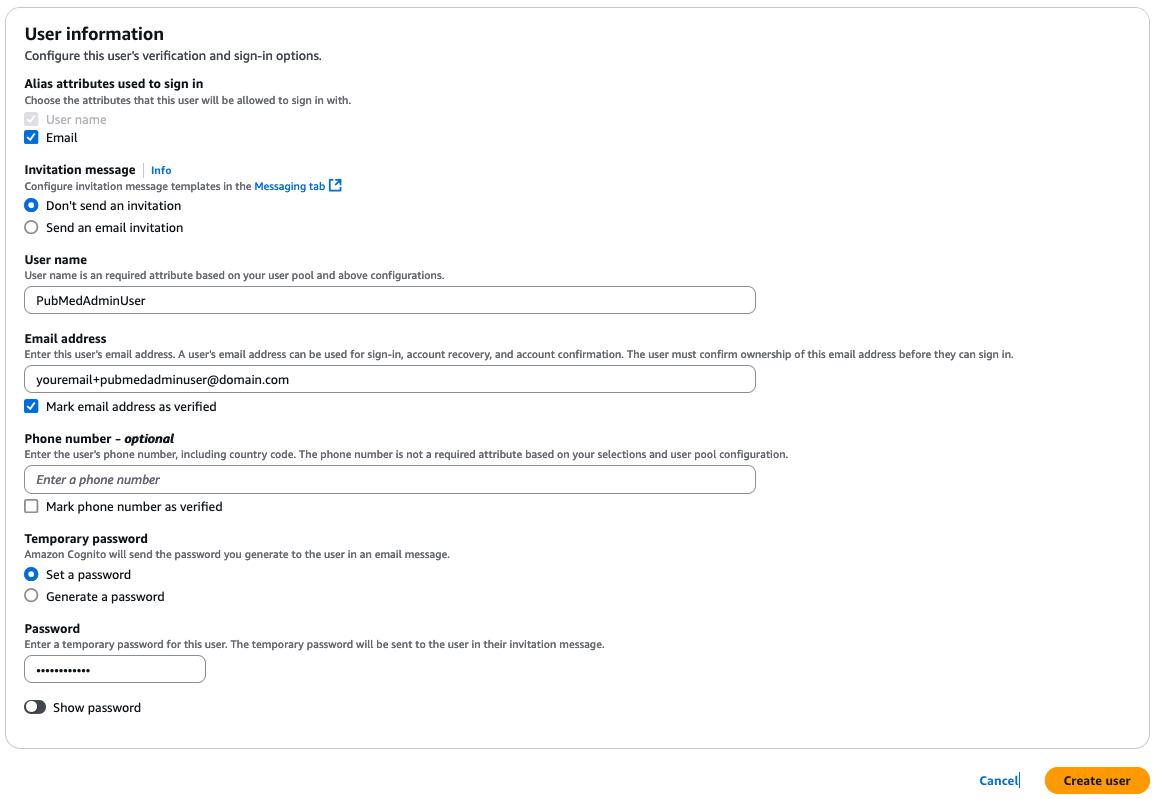
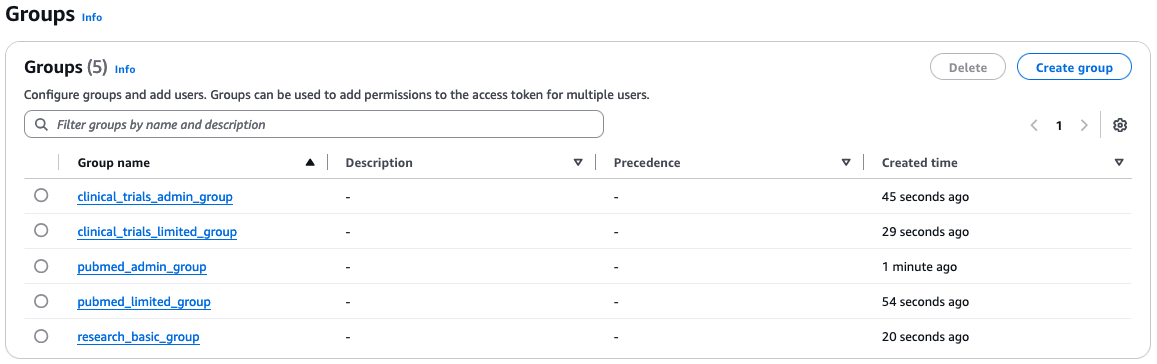
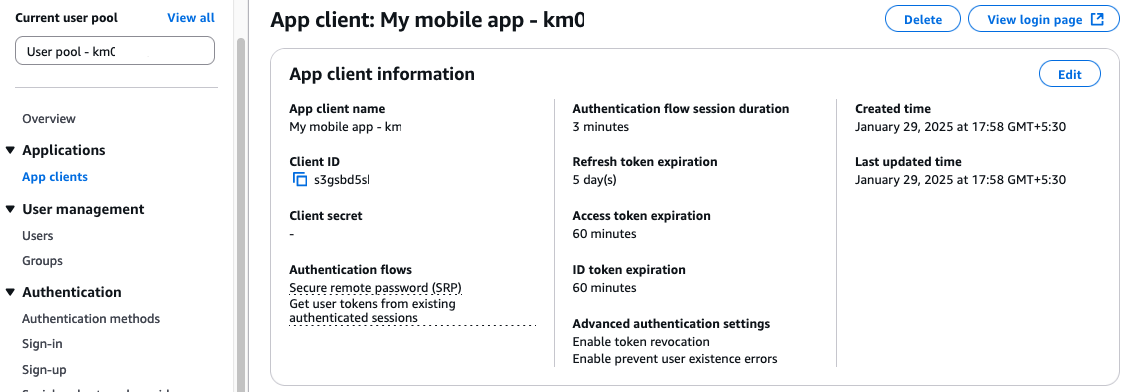
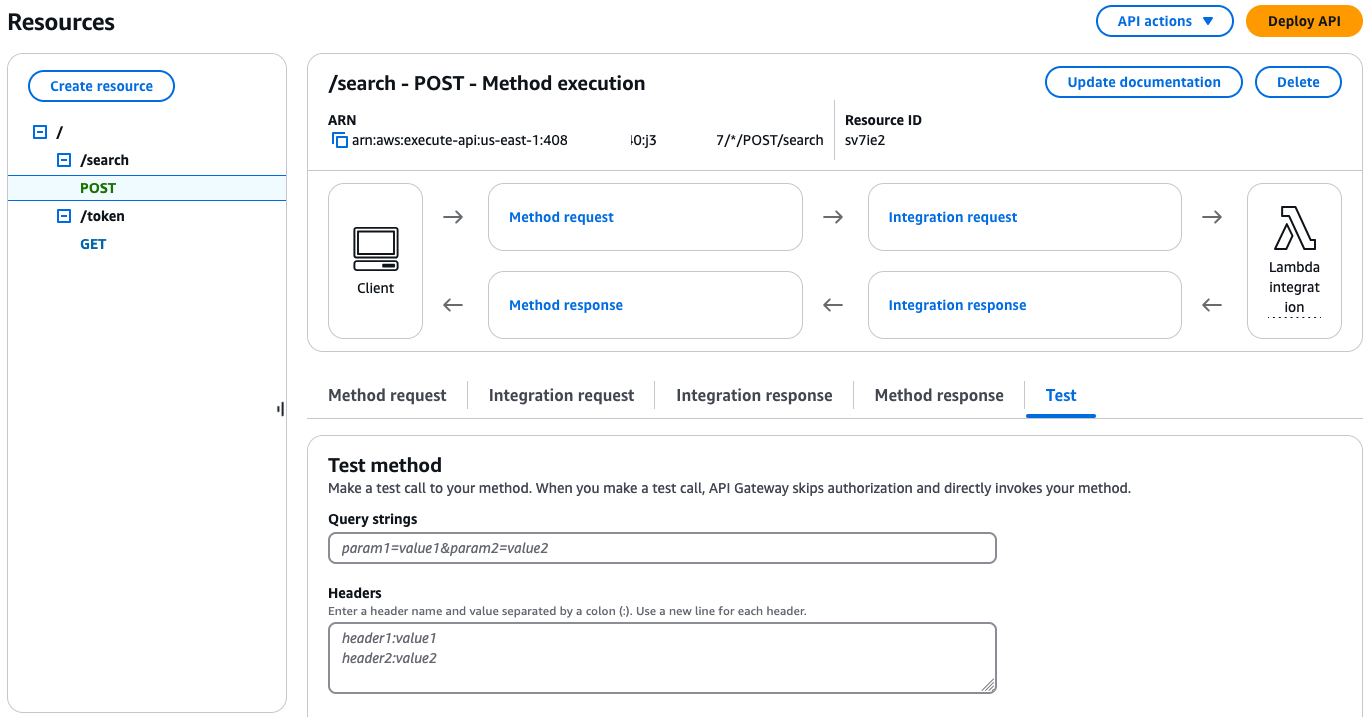
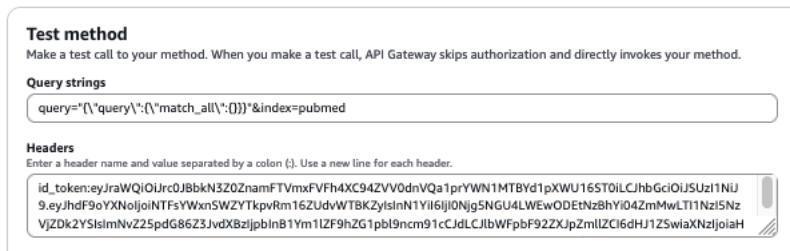
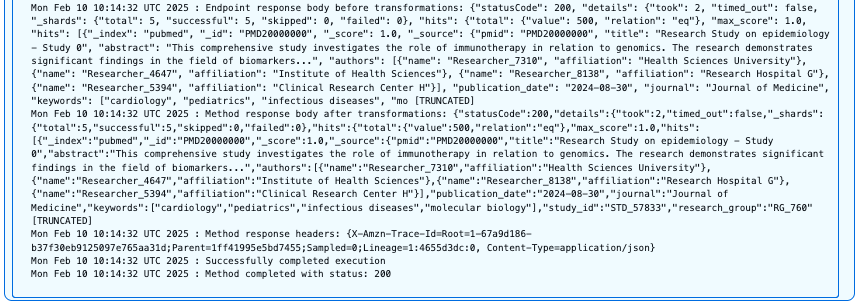
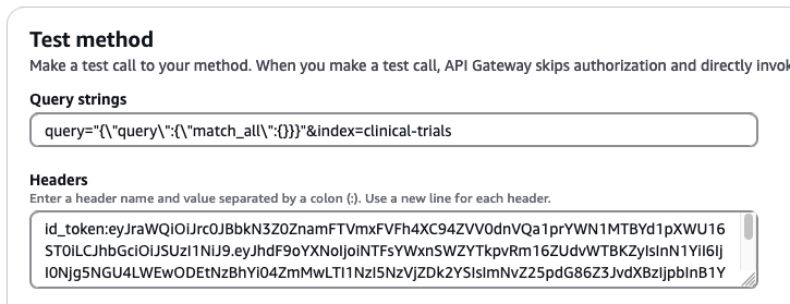
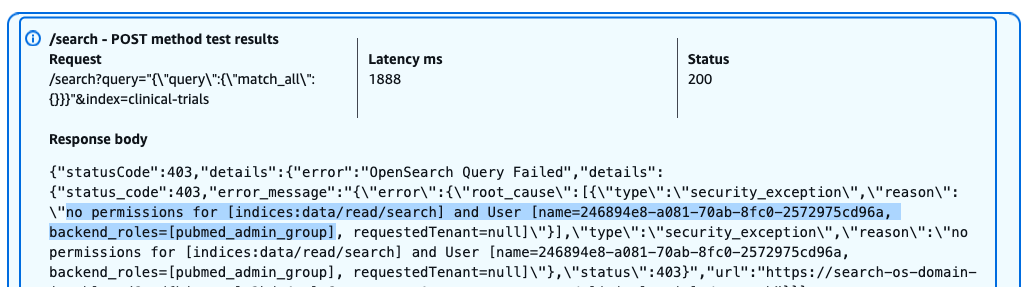
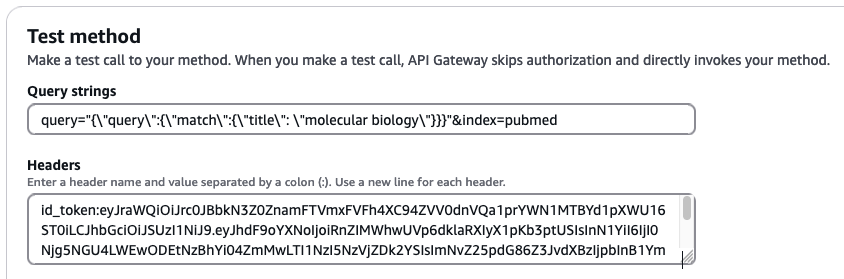
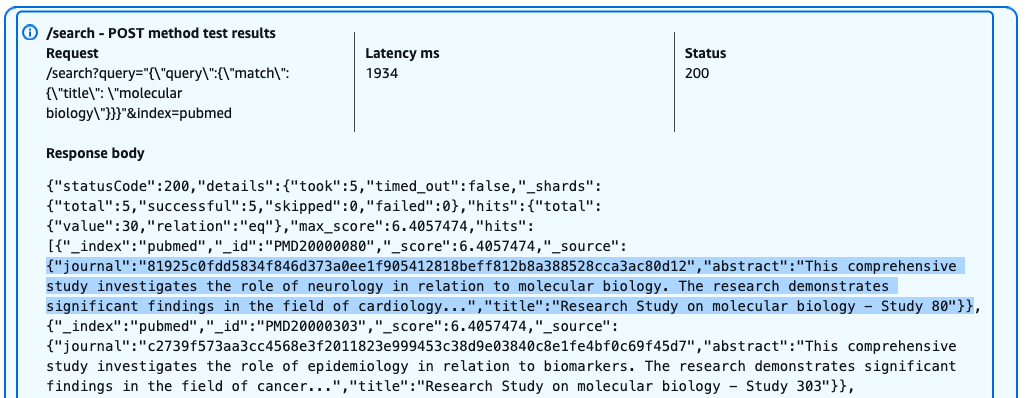
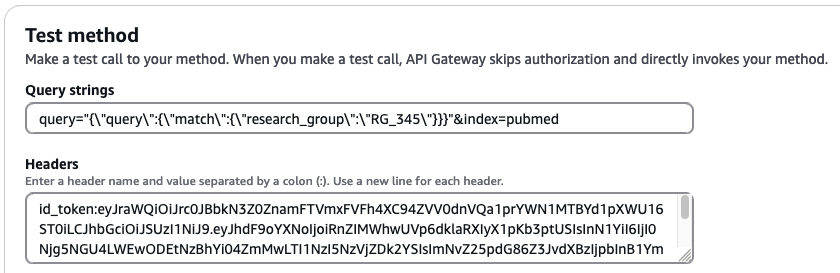
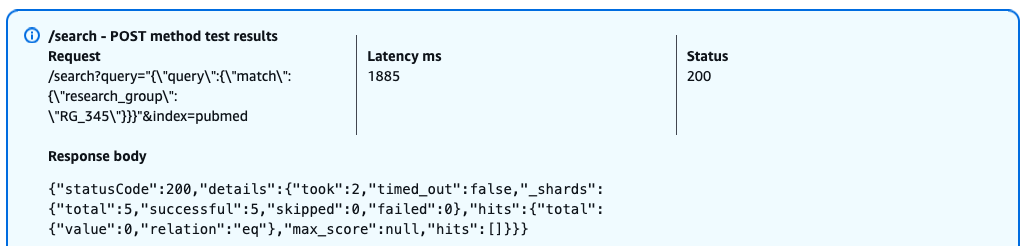
 Ramya Bhat is a Data Analytics Consultant at AWS, specializing in the design and implementation of cloud-based data platforms. She builds enterprise-grade solutions across search, data warehousing, and ETL that enable organizations to modernize data ecosystems and derive insights through scalable analytics. She has delivered customer engagements across healthcare, insurance, fintech, and media sectors.
 Shubhansu Sawaria is a Sr. Delivery Consultant – SRC at AWS, based in Bangalore, India. He specializes in designing and implementing comprehensive AWS Cloud security solutions. He has developed security solutions for startups, banks, and healthcare organizations. His expertise helps organizations elevate their cloud security infrastructures, achieve compliance objectives, and provide robust data protection.
 Soujanya Konka is a Sr. Solutions Architect and Analytics Specialist at AWS, focused on helping customers build their ideas in the cloud. She has expertise in designing and implementing enterprise search solutions and advanced data analytics at scale.
 Martin Milenkoski is a Software Development Engineer on the Amazon Redshift team, currently focusing on data lake performance and query optimization. Martin holds an MSc in Computer Science from the École Polytechnique Fédérale de Lausanne.
 Kalaiselvi Kamaraj is a Sr. Software Development Engineer on the Amazon Redshift team. She has worked on several projects within the Amazon Redshift Query processing team and currently focusing on performance related projects for Amazon Redshift DataLake and query optimizer.
 Jonathan Katz is a Principal Product Manager – Technical on the AWS Analytics team and is based in New York. He is a Core Team member of the open-source PostgreSQL project and an active open-source contributor, including to the pgvector project.
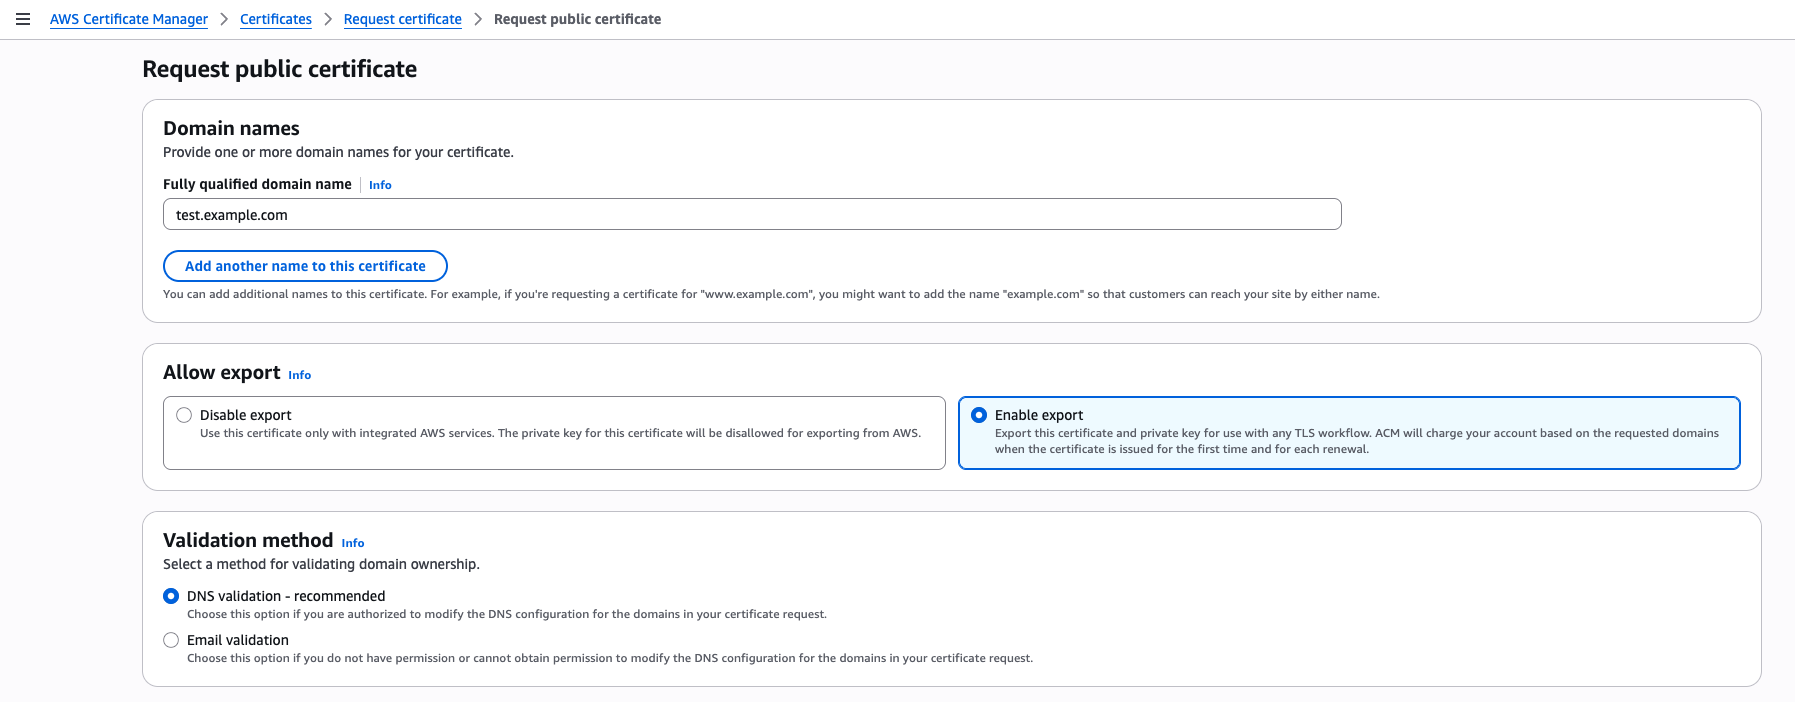
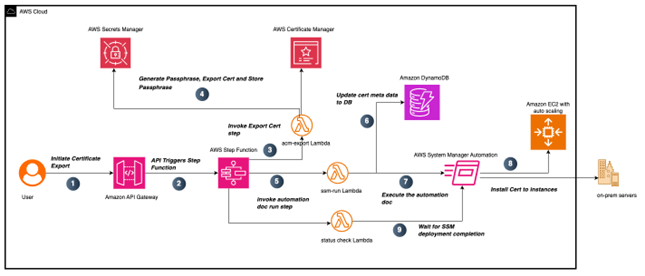
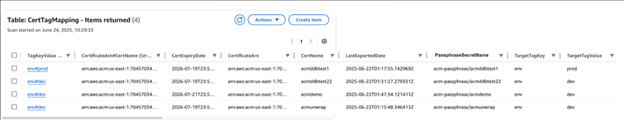
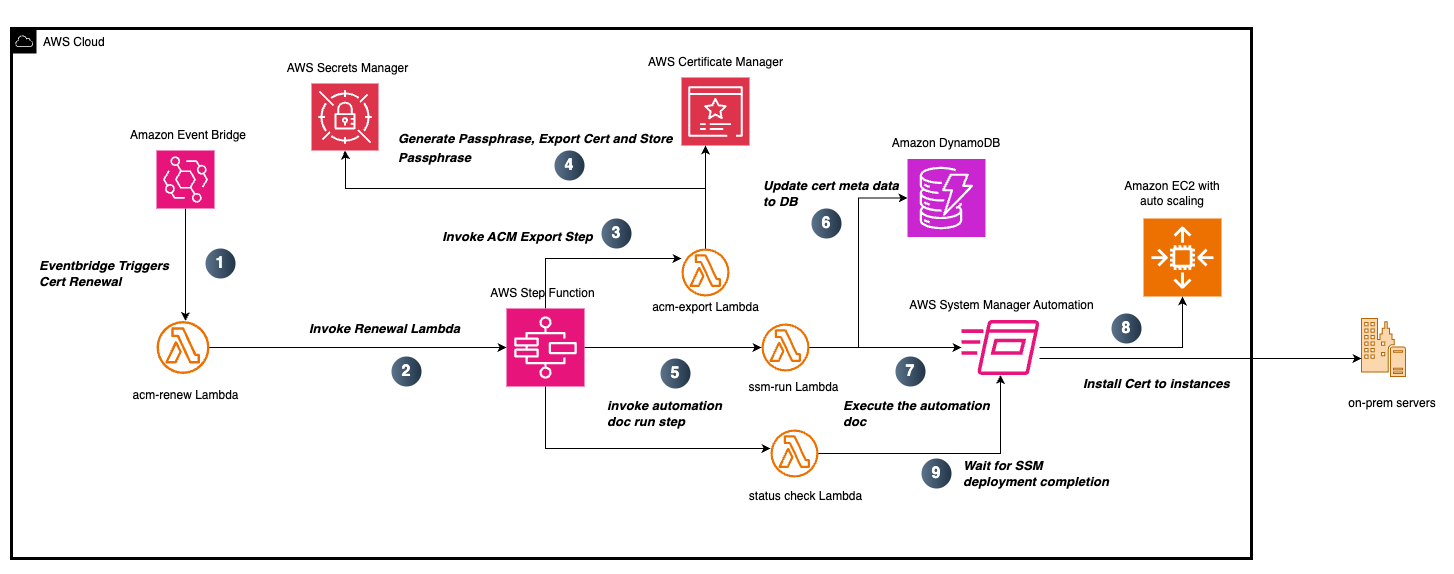


 Masudur Rahaman Sayem is a Streaming Data Architect at AWS with over 25 years of experience in the IT industry. He collaborates with AWS customers worldwide to architect and implement sophisticated data streaming solutions that address complex business challenges. As an expert in distributed computing, Sayem specializes in designing large-scale distributed systems architecture for maximum performance and scalability. He has a keen interest and passion for distributed architecture, which he applies to designing enterprise-grade solutions at internet scale.


 Raj Ramasubbu is a Senior Analytics Specialist Solutions Architect focused on big data and analytics and AI/ML with Amazon Web Services. He helps customers architect and build highly scalable, performant, and secure cloud-based solutions on AWS. Raj provided technical expertise and leadership in building data engineering, big data analytics, business intelligence, and data science solutions for over 18 years prior to joining AWS. He helped customers in various industry verticals like healthcare, medical devices, life science, retail, asset management, car insurance, residential REIT, agriculture, title insurance, supply chain, document management, and real estate.
 Francisco Morillo is a Streaming Solutions Architect at AWS. Francisco works with AWS customers, helping them design real-time analytics architectures using AWS services, supporting Amazon Managed Streaming for Apache Kafka (Amazon MSK) and Amazon Managed Service for Apache Flink.
 Ismail Makhlouf is a Senior Specialist Solutions Architect for Data Analytics at AWS. Ismail focuses on architecting solutions for organizations across their end-to-end data analytics estate, including batch and real-time streaming, big data, data warehousing, and data lake workloads. He primarily partners with airlines, manufacturers, and retail organizations to support them to achieve their business objectives with well-architected data platforms.


 Sai Maddali is a Senior Manager Product Management at AWS who leads the product team for Amazon MSK. He is passionate about understanding customer needs, and using technology to deliver services that empowers customers to build innovative applications. Besides work, he enjoys traveling, cooking, and running.
 Nagarjuna Koduru is a Principal Engineer in AWS, currently working for AWS Managed Streaming For Kafka (MSK). He led the teams that built MSK Serverless and MSK Tiered storage products. He previously led the team in Amazon JustWalkOut (JWO) that is responsible for real time tracking of shopper locations in the store. He played pivotal role in scaling the stateful stream processing infrastructure to support larger store formats and reducing the overall cost of the system. He has keen interest in stream processing, messaging and distributed storage infrastructure.
 Masudur Rahaman Sayem is a Streaming Data Architect at AWS. He works with AWS customers globally to design and build data streaming architectures to solve real-world business problems. He specializes in optimizing solutions that use streaming data services and NoSQL. Sayem is very passionate about distributed computing.


 Balaram Mathukumilli is Director, Enterprise Data Services at DISH Wireless. He is deeply passionate about Data and Analytics solutions. With 20+ years of experience in Enterprise and Cloud transformation, he has worked across domains such as PayTV, Media Sales, Marketing and Wireless. Balaram works closely with the business partners to identify data needs, data sources, determine data governance, develop data infrastructure, build data analytics capabilities, and foster a data-driven culture to ensure their data assets are properly managed, used effectively, and are secure
 Viswanatha Vellaboyana, a Solutions Architect at DISH Wireless, is deeply passionate about Data and Analytics solutions. With 20 years of experience in enterprise and cloud transformation, he has worked across domains such as Media, Media Sales, Communication, and Health Insurance. He collaborates with enterprise clients, guiding them in architecting, building, and scaling applications to achieve their desired business outcomes.
 Keerthi Kambam is a Senior Engineer at DISH Network specializing in AWS Services. She builds scalable data engineering and analytical solutions for dish customer faced applications. She is passionate about solving complex data challenges with cloud solutions.
 Raks Khare is a Senior Analytics Specialist Solutions Architect at AWS based out of Pennsylvania. He helps customers across varying industries and regions architect data analytics solutions at scale on the AWS platform. Outside of work, he likes exploring new travel and food destinations and spending quality time with his family.
 Adi Eswar has been a core member of the AI/ML and Analytics Specialist team, leading the customer experience of customer’s existing workloads and leading key initiatives as part of the Analytics Customer Experience Program and Redshift enablement in AWS-TELCO customers. He spends his free time exploring new food, cultures, national parks and museums with his family.
 Shirin Bhambhani is a Senior Solutions Architect at AWS. She works with customers to build solutions and accelerate their cloud migration journey. She enjoys simplifying customer experiences on AWS.
 Vinayak Rao is a Senior Customer Solutions Manager at AWS. He collaborates with customers, partners, and internal AWS teams to drive customer success, delivery of technical solutions, and cloud adoption.


 ML-powered search with OpenSearch
 Praveen Mohan Prasad is an Analytics Specialist Technical Account Manager at Amazon Web Services and helps customers with pro-active operational reviews on analytics workloads. Praveen actively researches on applying machine learning to improve search relevance.
 Hajer Bouafif is an Analytics Specialist Solutions Architect at Amazon Web Services. She focuses on Amazon OpenSearch Service and helps customers design and build well-architected analytics workloads in diverse industries. Hajer enjoys spending time outdoors and discovering new cultures.
 Aruna Govindaraju is an Amazon OpenSearch Specialist Solutions Architect and has worked with many commercial and open-source search engines. She is passionate about search, relevancy, and user experience. Her expertise with correlating end-user signals with search engine behavior has helped many customers improve their search experience. Her favourite pastime is hiking the New England trails and mountains.


 Salim Tutuncu is a Sr. PSA Specialist on Data & AI, based from Amsterdam with a focus on the EMEA North and EMEA Central regions. With a rich background in the technology sector that spans roles as a Data Engineer, Data Scientist, and Machine Learning Engineer, Salim has built a formidable expertise in navigating the complex landscape of data and artificial intelligence. His current role involves working closely with partners to develop long-term, profitable businesses leveraging the AWS Platform, particularly in Data and AI use cases.
 Angel Conde Manjon is a Sr. PSA Specialist on Data & AI, based in Madrid, and focuses on EMEA South and Israel. He has previously worked on research related to Data Analytics and Artificial Intelligence in diverse European research projects. In his current role, Angel helps partners develop businesses centered on Data and AI.