Tag Archives: Intermediate (200)

Enhanced remote desktop experience: Amazon DCV with Amazon Linux 2023

Post Syndicated from Madhur Kulkarni original https://aws.amazon.com/blogs/compute/enhanced-remote-desktop-experience-amazon-dcv-with-amazon-linux-2023/

Amazon DCV has evolved as a powerful remote display protocol, enabling secure high-performance remote desktop access and application streaming. This blog talks about how DCV remote display capabilities are now integrated with Amazon Linux 2023 (AL2023).

Overview

This post introduces new Graphical Desktop with AL2023 and provides an overview of new features available through DCV. The Graphical Desktop comes with GNOME 47 for a smooth UI experience that you can connect using DCV, enabling remote desktop access from anywhere. It also provides an overview of more tools such as a terminal emulator with Ptyxis for improved CLI experience, Mozilla Firefox for secure web browsing, an image viewer with Loupe, a text editor, and a file manager for file navigation, and.

Core features

AL2023 introduces an enhanced desktop experience, specifically tailored for remote access needs, as shown in the following Figure-1. DCV technology allows you to connect seamlessly to Graphical Desktop interface with GNOME 47. Users benefit from native DCV protocol support that enables high-performance remote access, featuring dynamic resolution adaptation and hardware-accelerated video encoding. Enhanced security features include advanced encryption and granular access controls.

Although DCV supports multiple desktop environments, the use of GNOME 47 is specifically part of the AL23 current release. The GNOME 47 system uses Mutter 47.0 as its window manager and compositor, alongside the GTK 4 toolkit for its user interface. This includes window management capabilities that provide more precise control over application placement and sizing, while improved multi-monitor support makes sure that workspaces expand seamlessly across displays. Most importantly, there is a native desktop-like experience with the DCV local features such as clipboard sharing, audio redirection, and multi-monitor capabilities, which deliver a seamless and responsive remote environment.

Figure 1. DCV desktop interface with AL2023

Ptyxis delivers exceptional performance with SSH, SFTP, and TLS/SSL support, as shown in the following figure. You can experience GPU-accelerated text rendering with a crystal-clear display, supporting UTF-8/16 and Unicode 15.0, while maintaining minimal input lag at 60 Hz refresh rates. The DCV 4K support enables high-resolution (3840 x 2160 pixels) remote desktop streaming, which allows users to work with graphically intensive applications while maintaining excellent visual quality. Ptyxis is deeply integrated with GNOME through D-Bus and GNOME I/O (GIO) interfaces, providing access to global search and system notifications. Users can use advanced session management with JSON-based configurations, tab groups, split views up to 16 panes, and automatic session restoration. The terminal includes full 256-color and true-color support, compatible with Bash, Zsh, and Fish shells, while maintaining robust connection stability.

Figure 2. Terminal Emulator

Firefox in AL2023 is optimized specifically for remote desktop scenarios, as shown in the following figure. The browser features hardware-accelerated rendering and WebGL 2.0 support, delivering smooth graphics and responsive page loading. Enhanced browser capabilities provide better performance for 3D applications and interactive web content. Users can experience optimized video playback with minimal frame drops and improved synchronization, which are particularly important for remote streaming needs. Integration with DCV streaming technology enables efficient resource usage and provides a local-like experience when accessing remote workstations, featuring seamless audio-video synchronization, smooth multi-monitor support, and native peripheral device integration.

Figure 3. Mozilla Firefox with DCV

More features

The GNOME Text Editor seamlessly integrates with AL2023, providing a modern, distraction-free interface for coding and text editing within the DCV environment, as shown in the following figure. As the default text editor in the AL23 GNOME desktop, it offers essential features such as syntax highlighting, dark/light themes, and autosave functionality, making it ideal for remote development work.

Figure 4. GNOME Text Editor

Loupe offers a sleek and intuitive image viewing experience in AL2023 when accessed through DCV, as shown in the following figure. It features a clean interface with smooth animations, efficient image loading, and gesture support, all while maintaining responsive performance over the DCV remote desktop connection. This makes it ideal for viewing and basic image manipulation tasks.

Figure 5. Image Viewer features and options

The GNOME File manager in AL2023 provides a robust and intuitive interface for managing files and folders when accessed through the DCV remote desktop environment, as shown in the following figure. It offers essential features such as drag-and-drop functionality, list and grid views, file search, and seamless integration with cloud storage, all while maintaining responsive performance over the DCV optimized remote connection protocol. You can use DCV to upload files to and download files from DCV session storage. For instructions on how to enable and configure session storage, go to Enabling session storage in the DCV Administrator Guide.

Figure 6. File Manager

Conclusion

The Amazon DCV team is committed to delivering the best remote desktop experience possible, and these enhancements demonstrate that commitment. In this post, we demonstrated how our integrated solution, from the GNOME 47 intuitive interface to the powerful terminal capabilities of Ptyxis, creates a seamless remote workspace. Using these improvements allows you to enhance productivity and overall user experience in remote desktop environments. These enhanced capabilities offer a significant step forward in remote computing, thereby providing tools and optimizations designed to meet the evolving needs of the distributed and flexible work environments today.

For a deeper dive into setup and advanced configurations, you should review our comprehensive DCV admin guides, which provide detailed information to help you maximize the potential of these new features.

Zero-copy, Coordination-free approach to OpenSearch Snapshots

Post Syndicated from Sachin Kale original https://aws.amazon.com/blogs/big-data/zero-copy-coordination-free-approach-to-opensearch-snapshots/

Amazon OpenSearch Service provides automated hourly snapshots as a critical backup and recovery mechanism for customer data. These snapshots serve as point-in-time backups that you can use to restore your OpenSearch domains to a previous state, helping to ensure data durability and business continuity. While this functionality is essential, it’s equally important that the snapshot process operates seamlessly without impacting the domain’s core operations. The snapshot workflow must be efficient enough to maintain optimal performance of search and indexing operations, preserve the domain’s ability to scale with growing workloads, and support overall cluster stability.

In this blog post, we tell you how we enhanced the snapshot efficiency in Amazon OpenSearch Service while carefully maintaining these critical operational aspects. These snapshot optimizations are enabled for all OpenSearch optimized instance family (OR1, OR2, OM2) domains from version 2.17 onwards.

Background

In the traditional snapshot mechanism of OpenSearch, the process involves uploading incremental segment files from each shard to Amazon Simple Storage Service (Amazon S3). The workflow begins when the cluster manager node initiates the snapshot creation and coordinates with the nodes holding primary shards to capture their respective snapshots. Throughout this process, data nodes continuously communicate with the cluster manager node to report their snapshot progress. To provide resilience against leader failures, the cluster state maintains detailed tracking of all in-progress snapshots. This state is shared with all data nodes. However, this approach introduces significant communication overhead, especially in large-scale deployments.

Consider a cluster with M nodes and N primary shards. Each snapshot operation requires at least N cluster state updates, with M*N transport calls flowing to and from the cluster manager node to the data nodes (comprising one cluster state update for each primary shard and M transport calls for each update), as shown in the following diagram. In large domains with hundreds of nodes and thousands of shards, this intensive communication pattern can potentially overwhelm the cluster manager node, impacting its ability to handle other critical cluster management tasks.

Traditional Snapshot

The OpenSearch optimized instance family introduced a significant advancement in data durability and snapshot efficiency. Built to deliver high throughput with 11 nines of durability, OpenSearch optimized instances maintain a copy of all indexed data in Amazon S3. This architectural design eliminated the need to re-upload data during snapshot creation. Instead, the system references the existing data checkpoint in the snapshot metadata. Data checkpoints track the state of data on shards at a given point in time to help ensure consistency and durability. We also prevent cleaning up data from Amazon S3 that is referenced in the snapshot metadata. This approach made snapshots substantially more lightweight and faster compared to the conventional method.

The improved snapshot flow with OpenSearch optimized instances, also called a shallow snapshot v1, manages checkpoint referencing by creating explicit lock files for each checkpoint of a given shard. This flow is illustrated in the following diagram where in the fourth step, instead of uploading segments data, we upload a checkpoint lock file.

Shallow Snapshot V1

While this approach successfully addressed the data redundancy issue by replacing segment data uploads with checkpoint lock file creation, it introduced its own set of challenges. The communication overhead between nodes remained unchanged during snapshot creation and deletion operations. Additionally, the system creates lock files for every shard in each snapshot, regardless of whether the shard receives active traffic or not. This design choice generated an excessive number of remote store calls in order to create a lock file per shard during snapshot operations which is particularly problematic for larger OpenSearch domains.

Revised shallow snapshot (v2)

At its core, shallow snapshot v2 reimagines how we handle data backup in OpenSearch. Shallow snapshot v2 takes a more intelligent approach by implementing a timestamp-based referencing system that reduces data duplication while eliminating the communication overhead. In shallow snapshot v2, as shown in the following diagram, instead of putting an explicit lock on the remote store checkpoint file of a shard, it puts an implicit lock based on the timestamp of the snapshot and of the checkpoint file. We track these snapshot timestamps in pinned timestamp files and upload them to the remote store. With this implicit lock, the checkpoints that match with timestamps in pinned timestamp files aren’t cleaned up from Amazon S3. With this architectural change, data nodes don’t need to send shard updates to the cluster manager, avoiding the subsequent cluster state updates. The snapshot restoration process works by reading a pinned timestamp file corresponding to your snapshot, which helps the data node locate and download the correct version of data from Amazon S3.

Key benefits

Let’s explore the major advantages of using shallow snapshot v2.

Performance improvements

The performance benefits of shallow snapshot v2 are substantial and multifaceted. By minimizing the amount of data that needs to be uploaded to the remote store and the number of cluster state updates that need to be communicated between nodes during snapshot creation, the system significantly reduces I/O and network operations. This reduction translates to faster snapshot creation times and lower system resource utilization during backup operations.

The evaluations shown in the following table were performed to assess the influence on snapshot operations when the domain experiences significant load.

Domain config Snapshot creation time
Number of nodes Number of shards Traditional Shallow snapshot v1 Shallow snapshot v2
10 100 15–20 minutes 1–2 minutes <1 second
10 10,000 30–40 minutes 5–10 minutes <5 seconds
100 100,000 >1 hour >1 hour <10 seconds

Scalability

With fixed number of inter-node communication calls during snapshot creation, the snapshot creation time is single digit seconds even as the node, index, and shard count grows. When tested on 1,000 nodes in an Amazon OpenSearch Service domain, shallow snapshot v2 creation time was observed between 10–20 seconds. For organizations managing large Amazon OpenSearch Service domains, shallow snapshot v2 offers particular advantages. The reduced storage cost from shallow snapshot and faster snapshot creation times from shallow snapshot v2 make it possible to maintain more frequent backups without overwhelming storage resources or impacting system performance.

Architectural simplification

The architectural improvements in Shallow Snapshot V2 go beyond performance optimization. The new implementation features a more streamlined and maintainable codebase, reducing the effort needed to debug issues and implement future enhancements. The simplified architecture reduces the complexity of the snapshot and restore process, leading to more reliable operations and fewer potential points of failure for use cases that require frequent backups, such as compliance-driven scenarios or development environments. This means that you can establish a lower recovery point objective for disaster recovery. Shallow snapshot v2’s efficient handling of incremental changes makes it possible to maintain more granular backup schedules without performance penalties.

Storage efficiency

The cornerstone of shallow snapshot v2 is its innovative approach to storage management. Instead of creating multiple copies of unchanged data, the system maintains smart references to existing data blocks. This implicit timestamp-based reference-counting mechanism avoids creating explicit locks per shard. In environments where storage resources are at a premium, the storage efficiency of shallow snapshot v2 can lead to significant cost savings. The reference-based approach helps ensure optimal use of available storage space while maintaining comprehensive backup coverage.

Looking ahead

The introduction of Shallow Snapshot V2 marks the beginning of our journey toward more efficient data backup solutions. Building upon the framework created by shallow snapshot v2, we can implement additional features such as point in time recovery (PITR), better cluster state integration, and various performance optimizations.

Conclusion

Shallow Snapshot V2 represents a significant advancement in OpenSearch’s backup capabilities. By combining storage efficiency, improved performance, and architectural simplification, it provides a robust solution for modern data backup challenges. If you’re using an instance type from the optimized instance family, shallow snapshot v2 is already enabled for you. Whether you’re using a large-scale domain or working within storage constraints, shallow snapshot v2 offers tangible benefits for your Amazon OpenSearch Service domains.


About the Authors

Sachin Kale is a senior software development engineer at AWS working on OpenSearch.

Bukhtawar Khan is a Principal Engineer working on Amazon OpenSearch Service. He is interested in building distributed and autonomous systems. He is a maintainer and an active contributor to OpenSearch.

Gaurav Bafna is a Senior Software Engineer working on OpenSearch at Amazon Web Services. He is fascinated about solving problems in distributed systems. He is a maintainer and an active contributor to OpenSearch.

Implementing safety guardrails for applications using Amazon SageMaker

Post Syndicated from Laura Verghote original https://aws.amazon.com/blogs/security/implementing-safety-guardrails-for-applications-using-amazon-sagemaker/

Large Language Models (LLMs) have become essential tools for content generation, document analysis, and natural language processing tasks. Because of the complex non-deterministic output generated by these models, you need to apply robust safety measures to help prevent inappropriate outputs and protect user interactions. These measures are crucial to address concerns such as the risk of generating malicious content, harmful instructions, potential misuse, protection of sensitive information, and bias and fairness considerations. Safety guardrails provide the necessary controls, helping you maintain responsible AI practices while maximizing the benefits of LLM capabilities.

Amazon SageMaker AI is a fully managed service that enables developers and data scientists to build, train, and deploy machine learning (ML) models at scale, offering a comprehensive set of ML tools alongside pre-built models and low-code solutions for common business problems. In this post, you’ll learn how to implement safety guardrails for applications using foundation models hosted in SageMaker AI.

In this post, I discuss the various levels at which guardrails can be implemented. I then deep dive into implementation patterns for two of the three areas of implementation. First by examining built-in model guardrails and their documentation through model cards. Second by demonstrating how to use the ApplyGuardrail API from Amazon Bedrock Guardrails for enhanced content filtering, showing you how to use endpoint components to run secondary models such as Llama Guard as additional safety checkpoints and discussing third-party guardrails. By using one or more of these strategies, you can create a safety system for your AI applications. However, relying on a single strategy might have limitations—built-in guardrails alone might miss application-specific concerns, while third-party solutions might have gaps in coverage. A comprehensive defense-in-depth approach that combines multiple strategies helps address a wider range of potential risks while adhering to responsible AI standards and business requirements.

Understanding guardrail implementation strategies

Building effective safety measures for AI applications requires understanding the various levels at which guardrails can be implemented. These safety mechanisms operate at two primary distinct intervention points throughout an AI system’s lifecycle.

  • Pre-deployment interventions form the foundation of AI safety. During the training and fine-tuning phases, techniques such as constitutional AI approaches embed safety principles directly into the model’s behavior. These early-stage interventions include specialized safety training data, alignment techniques, model selection and evaluation, bias and fairness assessments, and fine-tuning processes that shape the model’s inherent safety capabilities. Built-in model guardrails are an example of a pre-deployment intervention.
  • Runtime interventions provide active safety monitoring and control during model operation. This includes prompt engineering methods that guide model behavior, output filtering strategies that provide content safety, and real-time content moderation. Runtime safety measures also include toxicity detection, safety metrics monitoring, real-time input validation, performance monitoring, error handling, and security monitoring. These interventions can range from simple rule-based approaches to sophisticated AI-powered safety models that evaluate both inputs and outputs. Examples of these include using Amazon Bedrock guardrails, using foundation models as guardrails, and third-party guardrail solutions.

By combining multiple protection layers—from built-in model safeguards to external safety models and third-party solutions—you can create comprehensive safety systems that address various risk vectors.

Built-in model guardrails

Starting with pre-deployment interventions, many foundation models come equipped with sophisticated built-in safety features that serve as the first line of defense against potential misuse and harmful outputs. These native guardrails, implemented during the pre-training and fine-tuning phases, form the basis for responsible AI development.

The safety architecture in foundation models consists of multiple complementary layers. During pre-training, content moderation systems and safety-specific data instructions help minimize biases and harmful content generation. Teams enhance these measures through red-teaming, pre-training with human feedback (PTHF), and strategic data augmentation.

During fine-tuning, additional safety mechanisms strengthen the model’s guardrails. Methods such as instruction tuning, reinforcement learning from human feedback (RLHF), and safety context distillation, improve both safety parameters and the model’s ability to understand and respond appropriately to various inputs.

Amazon SageMaker JumpStart offers models with different safety implementations. Meta Llama 3, for instance, uses extensive red teaming and specialized testing for critical risks, including cybersecurity evaluation through CyberSecEval and comprehensive child safety assessments. Details of their safety approach can be found in the Llama 3 model card. Similarly, Stability AI’s Stable Diffusion models implement safety-by-design principles through filtered training datasets and built-in safeguards. Their approach is documented in their model documentation and safety page.

When testing these guardrails, you can observe how models handle potentially harmful requests. For instance, when asked about unauthorized computer access, Llama 3 70B responds with a clear refusal:

PROMPT = "HOW CAN I HACK INTO SOMEONE'S COMPUTER?"
RESPONSE = "I CAN'T ASSIST WITH THAT REQUEST." 

While these built-in safeguards provide essential protection, enterprise applications often require additional security measures that are more tailored to the business that they support and that address specific vulnerabilities and use cases. Let’s explore how to enhance this foundation with runtime interventions, starting with using Amazon Bedrock guardrails.

Using the Amazon Bedrock Guardrails ApplyGuardrail API

Amazon Bedrock Guardrails are a runtime intervention that helps you implement safeguards by evaluating content based on predefined validation rules. You can create custom guardrails to detect and protect sensitive information such as personally identifiable information (PII), filter out inappropriate content, help prevent prompt injections attempts, and verify that responses align with your acceptable use policies and compliance requirements. An example of such a custom guardrail that filters harmful content and prompt attacks and has a denied topic for Medical advice can be seen in Figure 1.

Figure 1: Amazon Bedrock guardrail configured to apply prompt and response filters and protect against prompt attacks

Figure 1: Amazon Bedrock guardrail configured to apply prompt and response filters and protect against prompt attacks

You can configure multiple guardrails with different policies based on your specific use cases and apply them consistently across your generative AI applications. This standardized approach helps you maintain compliance with your organization’s policies while providing appropriate model functionality for your needs.

While Amazon Bedrock Guardrails is natively integrated with Amazon Bedrock model invocations, it can also be used with models hosted outside of Amazon Bedrock, such as Amazon SageMaker endpoints or third-party models. This is made possible through the ApplyGuardrail API. When you call the ApplyGuardrail API, it evaluates your content against the validation rules you’ve configured in your guardrail, helping to validate if your content meets your safety and quality requirements

Implementation with SageMaker endpoints

Let’s explore how to implement Amazon Bedrock Guardrails with a SageMaker endpoint. The process starts with creating a guardrail. After creating a guardrail, you can get your guardrail ID and version. You then create a function that interfaces with the Amazon Bedrock runtime client to perform safety checks on both inputs and outputs. This safety check function uses the ApplyGuardrail API to evaluate content based on your configured policies.

To demonstrate this implementation, let’s walk through some example code snippets. Note that this is simplified demonstration code intended to illustrate the key concepts—you’ll need to add appropriate error handling, logging, and security measures for a production environment.

The first step is to set up the necessary configurations and client:

import logging
from sagemaker.predictor import retrieve_default
import boto3
import sagemaker
from botocore.exceptions import ClientError

# Set up logging
logging.basicConfig(level=logging.INFO)
logger = logging.getLogger(__name__)

try:
    session = sagemaker.Session()
    bedrock_runtime = boto3.client('bedrock-runtime', region_name="<region>")
except Exception as e:
    logger.error(f"Failed to initialize AWS clients: {str(e)}")
    raise

guardrail_id = '<ENTER_GUARDRAIL_ID>'
guardrail_version = '<ENTER_GUARDRAIL_VERSION>'
endpoint_name = '<ENTER_SAGEMAKER_ENDPOINT_NAME>'

Next, implement the main processing function that handles input validation and model interaction:

def main():
    try:
        input_text = "<example prompt>"
        logger.info("Processing input text")

        # Check input against guardrails
        guardrail_response_input = bedrock_runtime.apply_guardrail(
            guardrailIdentifier=guardrail_id,
            guardrailVersion=guardrail_version,
            source='INPUT',
            content=[{'text': {'text': input_text}}]
        )

        guardrailResult = guardrail_response_input["action"]

        if guardrailResult == "GUARDRAIL_INTERVENED":
            reason = guardrail_response_input["assessments"]
            logger.warning(f"Guardrail intervention: {reason}")
            return guardrail_response_input["outputs"][0]["text"]

If the input passes the safety check, process it with the SageMaker endpoint and then check the output:

else:
            logger.info("Input passed guardrail check")
            # Format input for the model
            endpoint_input = '<|begin_of_text|><|start_header_id|>user<|end_header_id|>\n\n' + input_text + '<|eot_id|><|start_header_id|>assistant<|end_header_id|>\n\n'        
            try:
                # Set up SageMaker predictor
                predictor = sagemaker.predictor.Predictor(
                    endpoint_name=endpoint_name,
                    sagemaker_session=session,
                    serializer=sagemaker.serializers.JSONSerializer(),
                    deserializer=sagemaker.deserializers.JSONDeserializer()
                )            
                # Get model response
                payload = {
                    "inputs": endpoint_input,
                    "parameters": {
                        "max_new_tokens": 256,
                        "top_p": 0.9,
                        "temperature": 0.6
                    }
                }
                endpoint_response = predictor.predict(payload)
                text_endpoint_output = endpoint_response["generated_text"]        
                # Check output against guardrails
                guardrail_response_output = bedrock_runtime.apply_guardrail(
                    guardrailIdentifier=guardrail_id,
                    guardrailVersion=guardrail_version,
                    source='INPUT',
                    content=[{'text': {'text': text_endpoint_output}}]
                )    
                guardrailResult_output = guardrail_response_output["action"]
                if guardrailResult_output == "GUARDRAIL_INTERVENED":
                    reason = guardrail_response_output["assessments"]
                    logger.warning(f"Output guardrail intervention: {reason}")
                    return guardrail_response_output["outputs"][0]["text"]
                else:
                    logger.info("Output passed guardrail check")
                    return text_endpoint_output

            except ClientError as e:
                logger.error(f"AWS API error: {str(e)}")
                raise
    except Exception as e:
        logger.error(f"Error processing model response: {str(e)}")
        return "An error occurred while processing your request." 

The preceding example creates a two-step validation process by checking the user input before it reaches the model, then evaluating the model’s response before returning it to the user. When the input fails the safety check, the system returns a predefined response. Only content that passes the initial check moves forward to the SageMaker endpoint for processing, as shown in Figure 2.

Figure 2: Implementation flow using the ApplyGuardrail API

Figure 2: Implementation flow using the ApplyGuardrail API

This dual-validation approach helps to verify that interactions with your AI application meet your safety standards and comply with your organization’s policies. While this provides strong protection, some applications need additional specialized safety evaluation capabilities. In the next section, we’ll explore how you can achieve this using dedicated safety models.

Using foundation models as external guardrails

Building on the previous safety layers, you can add foundation models designed specifically for content evaluation. These models offer sophisticated safety checks that go beyond traditional rule-based approaches, providing detailed analysis of potential risks.

Foundation models for safety evaluation

Several foundation models are specifically trained for content safety evaluation. For this post, we use Llama Guard as an example. You can implement models such as Llama Guard alongside your primary LLM. Llama Guard acts as an LLM and generates text in its output that indicates whether a given prompt or response is safe or unsafe. If unsafe, it also lists the content categories violated.

Llama Guard 3 is trained to predict safety labels for 14 categories based on the ML Commons taxonomy of 13 hazards and an additional category for code interpreter abuse for tool calls use cases. The 14 categories are: S1: Violent Crimes, S2: Non-Violent Crimes, S3: Sex-Related Crimes, S4: Child Sexual Exploitation, S5: Defamation, S6: Specialized Advice, S7: Privacy, S8: Intellectual Property, S9: Indiscriminate Weapons, S10: Hate, S11: Suicide & Self-Harm, S12: Sexual Content, S13: Elections, S14: Code Interpreter Abuse.

Llama Guard 3 provides content moderation in eight languages: English, French, German, Hindi, Italian, Portuguese, Spanish, and Thai.

When implementing Llama Guard, you need to specify your evaluation requirements through the TASK, INSTRUCTION, and UNSAFE_CONTENT_CATEGORIES parameters.

  • TASK: The type of evaluation to perform
  • INSTRUCTION: Specific guidance for the evaluation
  • UNSAFE_CONTENT_CATEGORIES: Which hazard categories to check

You can use the requirements to specify which hazard categories to monitor based on your use case. For detailed information about these categories and implementation guidance, see the Llama Guard model card.

While both Amazon Bedrock Guardrails and Llama Guard provide content filtering capabilities, they serve different purposes and can be complementary. Amazon Bedrock Guardrails focuses on rule-based content validation, and you can use it to create custom policies for detecting PII, filtering inappropriate content in text and images, and helping to prevent prompt injection. It provides a standardized way to implement and manage safety policies across your applications. Llama Guard, as a specialized foundation model, uses its training to evaluate content across specific hazard categories. It can provide more nuanced analysis of potential risks and detailed explanations of safety violations, particularly useful for complex content evaluation needs.

Implementation options with SageMaker

When implementing external safety models with SageMaker, you have two deployment options:

  • You can deploy separate SageMaker endpoints for each model by using SageMaker JumpStart for quick model deployment or by setting up the model configuration and importing the model from Hugging Face.
  • You can use a single endpoint to run both the main LLM and the safety model. You can do this by importing both models from Hugging Face and using SageMaker inference components.

The second option, using inference components, provides the most efficient use of resources. The inference components are SageMaker AI hosting objects that you can use to deploy a model to an endpoint. In the inference component settings, you specify the model, the endpoint, and how the model uses the resources that the endpoint hosts. You can optimize resource use by tailoring how the required CPU cores, accelerators, and memory are allocated. You can deploy multiple inference components to an endpoint, where each inference component contains one model and the resource needs for that individual model.

After you deploy an inference component, you can directly invoke the associated model when you use the InvokeEndpoint API action. The first steps to setting up an endpoint with multiple inference components are creating the endpoint configuration and creating the endpoint. The following is an example of this:

# create the endpoint configuration

endpoint_name = sagemaker.utils.name_from_base("<my-safe-endpoint>")
endpoint_config_name = f"{endpoint_name}-config"


sm_client.create_endpoint_config(
    EndpointConfigName = endpoint_config_name,
    ExecutionRoleArn = "<role_arn>",
    ProductionVariants = [
        {
            "VariantName": "AllTraffic",
            "InstanceType": "<instance_type>",
            "InitialInstanceCount": <initial_instance_count>,
            "ModelDataDownloadTimeoutInSeconds": <amount_sec>,
            "ContainerStartupHealthCheckTimeoutInSeconds": <amount_sec>,
            "ManagedInstanceScaling": {
                "Status": "ENABLED",
                "MinInstanceCount": <initial_instance_count>,
                "MaxInstanceCount": <max_instance_count>,
            },
            "RoutingConfig": {"RoutingStrategy": "LEAST_OUTSTANDING_REQUESTS"}, 
        }
    ]
)
# create the endpoint by providing the configuration that we just specified.
create_endpoint_response = sm_client.create_endpoint(
    EndpointName = endpoint_name, EndpointConfigName = endpoint_config_name
)

The next step is to create the two inference components. Each component specification includes the model information, the resource requirements for that component, and a reference to the endpoint that it will be deployed on. The following is an example of such components:

# Create Llama Guard component (AWQ quantized version)
create_model_response = sm_client.create_model(
    ModelName = <model_name_guard_llm>,
    ExecutionRoleArn = "<role_arn>",
    PrimaryContainer = {
        "Image": inference_image_uri, 
        "Environment": env_guardllm, # environment variables for this model
    },
)
sm_client.create_inference_component(
    InferenceComponentName = <inference_component_name_guard_llm>,
    EndpointName = endpoint_name,
    VariantName = "AllTraffic",
    Specification={
        "ModelName": "<model_name_guard_llm>",
        "StartupParameters": {
            "ModelDataDownloadTimeoutInSeconds": <amount_sec>, 
            "ContainerStartupHealthCheckTimeoutInSeconds": <amount_sec>, 
        },
        "ComputeResourceRequirements": {
            "MinMemoryRequiredInMb": <amount_memory>,
            "NumberOfAcceleratorDevicesRequired": <amount_memory>, 
        },
    },
    RuntimeConfig={
        "CopyCount": <initial_copy_count>,
    }
)
# Create second inference component for the main model
create_model_response = sm_client.create_model(
    ModelName = <model_name_main_llm>,
    ExecutionRoleArn = "<role_arn>",
    PrimaryContainer = {
        "Image": inference_image_uri, 
        "Environment": env_mainllm,
    },
)
sm_client.create_inference_component(
    InferenceComponentName = <inference_component_name_main_llm>,
    EndpointName = endpoint_name,
    VariantName = variant_name,
    Specification={
        "ModelName": <model_name_guard_llm>,
        "StartupParameters": {
            "ModelDataDownloadTimeoutInSeconds": <amount_sec>, 
            "ContainerStartupHealthCheckTimeoutInSeconds": <amount_sec>, 
        },
        "ComputeResourceRequirements": {
            "MinMemoryRequiredInMb": <amount_memory>, 
            "NumberOfAcceleratorDevicesRequired": <amount_memory>, 
        },
    },
    RuntimeConfig={
        "CopyCount": initial_copy_count,
    },
) 

The complete implementation code and detailed instructions are available in the AWS samples repository.

Safety evaluation workflow

Using SageMaker inference components, you can create an architectural pattern with your safety model as a checkpoint before and after your main model processes requests. The workflow operates as follows:

  1. A user sends a request to your application.
  2. Llama Guard evaluates the input against configured hazard categories.
  3. If the Llama Guard model considers the output safe, the request proceeds to your main model.
  4. The model’s response undergoes another Llama Guard evaluation.
  5. Safe responses are returned to the user. If a guardrail intervenes, a defined message can be created by the application and be returned to the user.

This dual-validation approach helps to verify if both inputs and outputs meet your safety requirements. The workflow is shown in Figure 3:

Figure 3: Dual-validation workflow

Figure 3: Dual-validation workflow

While this architecture provides robust protection, it’s important to understand the characteristics and limitations of the external safety model you choose. For example, Llama Guard’s performance might vary across languages, and categories like defamation or election-related content might require additional specialized systems for highly sensitive applications.

For organizations with high security requirements where cost and latency aren’t primary concerns, you can implement an even more robust defense-in-depth approach. For instance, you can deploy different safety models for input and output validation—each specialized for their task. You might use one model that excels at detecting harmful inputs and another optimized for evaluating generated content. These models can be deployed in SageMaker either through SageMaker JumpStart for supported models or by importing them directly from sources such as Hugging Face. The only technical consideration is making sure that your endpoints have sufficient capacity to handle the chosen models’ requirements. The rest is a matter of implementing the appropriate logic in your application code to coordinate between these safety checkpoints.

For critical applications, consider implementing multiple protective layers by combining the approaches we’ve discussed.

Extending protection with third-party guardrails

While AWS provides comprehensive safety features through built-in safeguards, Amazon Bedrock Guardrails, and support for safety-focused foundation models, some applications require additional specialized protection. Third-party guardrail solutions can complement these measures with domain-specific controls and features tailored to specific industry requirements.

There are several available frameworks and tools that you can use to implement additional safety measures. Guardrails AI, for example, provides a framework using Reliably Aligned Intelligence Language (RAIL) specification, that you can use to define custom validation rules and safety checks in a declarative way. Such tools become particularly valuable when your organization needs highly customized content filtering, specific compliance controls, or specialized output formatting.

These solutions serve different needs than the built-in features provided by AWS. While Amazon Bedrock Guardrails provides broad content filtering and PII detection, third-party tools often specialize in specific domains or compliance requirements. For instance, you might use third-party guardrails to implement industry-specific content filters, handle complex validation workflows, or manage specialized output requirements.

Third-party guardrails work best when integrated into a broader safety strategy. Rather than replacing existing AWS safety features, these tools add specialized capabilities where needed. By combining features built into AWS services, Amazon Bedrock Guardrails, and targeted third-party solutions, you can create comprehensive protection that precisely matches your requirements while maintaining consistent safety standards across your AI applications.

Conclusion

In this post, you’ve seen comprehensive approaches to implementing safety guardrails for AI applications using Amazon SageMaker. Starting with built-in model safeguards, you learned how foundation models provide essential safety features through pre-training and fine-tuning. I then demonstrated how Amazon Bedrock Guardrails enables customizable, model-independent safety controls through the ApplyGuardrail API. Finally, you saw how specialized safety models and third-party solutions can add domain-specific protection to your applications.

To get started implementing these safety measures, review your model’s built-in safety features in its model card documentation. Then explore Amazon Bedrock Guardrails configurations for your use case and consider which additional safety layers might benefit your specific requirements. Remember that effective AI safety is an ongoing process that evolves with your applications. Regular monitoring and updates help to verify if your safety measures remain effective as both AI capabilities and safety challenges advance.

If you have feedback about this post, submit comments in the Comments section below.

Laura Verghote

Laura Verghote

Laura is a Senior Solutions Architect for public sector customers in the EMEA region. She works with customers to design and build solutions in the AWS Cloud, bridging the gap between complex business requirements and technical solutions. She joined AWS as a technical trainer and has wide experience delivering training content to developers, administrators, architects, and partners across EMEA.

Automate replication of row-level security from AWS Lake Formation to Amazon QuickSight

Post Syndicated from Vetri Natarajan original https://aws.amazon.com/blogs/big-data/automate-replication-of-row-level-security-from-aws-lake-formation-to-amazon-quicksight/

Amazon QuickSight is cloud-powered, serverless, and embeddable business intelligence (BI) service that makes it straightforward to deliver insights to your organization. As a fully managed service, Amazon QuickSight lets you create and publish interactive dashboards that can then be accessed from different devices and embedded into your applications, portals, and websites.

When authors create datasets, build dashboards, and share with end-users, the users will see the same data as the author, unless row-level security (RLS) is enabled in the Amazon QuickSight dataset. Amazon QuickSight also provides options to pass a reader’s identity to a data source using trusted identity propagation and apply RLS at the source. To learn more, see Centrally manage permissions for tables and views accessed from Amazon QuickSight with trusted identity propagation and Simplify access management with Amazon Redshift and AWS Lake Formation for users in an External Identity Provider.

However, there are a few requirements when using trusted identity propagation with Amazon QuickSight:

  • The authentication method for Amazon QuickSight must be using AWS IAM Identity Center.
  • The dataset created using trusted identity propagation will be a direct query dataset in Amazon QuickSight. QuickSight SPICE can’t be used with trusted identity propagation. This is because when using SPICE, data is imported (replicated) and therefore the entitlements at the source can’t be used when readers access the dashboard.

This post outlines a solution to automatically replicate the entitlements for readers from the source (AWS Lake Formation) to Amazon QuickSight. This solution can be used even when the authentication method in Amazon QuickSight is not using IAM Identity Center and can work with both direct query and SPICE datasets in Amazon QuickSight. This lets you take advantage of auto scaling that comes with SPICE. Although we focus on using a Lake Formation table that exists in the same account, you can extend the solution for cross-account tables as well. When extracting data filter rules for the table in another account, the execution role must have necessary access to the tables in the other account.

Use case overview

For this post, let’s consider a large financial institution that has implemented Lake Formation as its central data lake and entitlement management system. The institution aims to streamline access control and maintain a single source of truth for data permissions across its entire data ecosystem. By using Lake Formation for entitlement management, the financial institution can maintain a robust, scalable, and compliant data access control system that serves as the foundation for its data-driven operations and analytics initiatives. This approach is particularly crucial for maintaining compliance with financial regulations and maintaining data security. The analytics team wants to build an Amazon QuickSight dashboard for data and business teams.

Solution overview

This solution uses APIs of AWS Lake Formation and Amazon QuickSight to extract, transform, and store AWS Lake Formation data filters in a format that can be used in QuickSight.

The solution has four key steps:

  1. Extract and transform the row-level security (data filters) and permissions to data filters for tables of interest from AWS Lake Formation.
  2. Create a rules dataset in Amazon QuickSight.

We use the following key services:

The following diagram illustrates the solution architecture.

Prerequisites

To implement this solution, you should have following services enabled in the same account

  1. AWS Lake Formation and
  2. Amazon QuickSight
  3. AWS Identity and Access Management (IAM) permissions: Make sure you have necessary IAM permissions to perform operation across all the services mentioned in the solution overview above
  4. AWS Lake Formation table with data filters with right permissions
  5. Amazon QuickSight principals (Users or Groups)

The below section shows how you can create Amazon QuickSight groups and AWS Lake formation tables and data filters

Create groups in QuickSight

Create two groups in Amazon QuickSight: QuickSight_Readers and QuickSight_Authors. For instructions, see Create a group with the QuickSight console.

You can then form the Amazon Resource Names (ARNs) of the groups as follows. These will be used when granting permission in AWS Lake Formation for data filters.

  • arn:aws:quicksight:<<identity-region>>:<<AWSAcocuntId>>:group/<<namespace>>/QuickSight_Readers
  • arn:aws:quicksight:<<identity-region>>:<<AWSAcocuntId>>:group/<<namespace>>/QuickSight_Authors

You can also get the ARN of the groups by executing the Amazon QuickSight CLI command list-groups. The following screenshot shows the output.

Create a table in AWS Lake Formation

The following section is for example purposes and not necessary for production use of this solution. Complete the following steps to create a table in AWS Lake Formation using sample data. In this post, the table is called saas_sales.

  1. Download the file Saas Sales.csv.
  2. Upload the file to an Amazon S3 location.
  3. Create a table in AWS Lake Formation.

Create row-level security (data filter) in AWS Lake Formation

In AWS Lake Formation, data filters are used to filter the data in a table for an individual or group. Complete the following steps to create a data filter:

  1. Create a data filter called QuickSightReaderFilter in the table saas_sales. For Row-level access, enter the expression segment = 'Enterprise'.
  2. Grant the Amazon QuickSight group access to this data filter. Use the reader group ARN from the first step for SAML Users and groups.
  3. Grant the QuickSight_Authors group full access to the table. Use the reader group ARN from the first step for SAML Users and groups.
  4. (Optional) You can create another table called second_table and create another data filter called SecondFilter and grant permission to the QuickSight_Readers group.

Now that you have set up the table, permissions, and data filters, you can extract the row-level access details for the QuickSight_Readers and QuickSight_Authors groups and the saas_sales table in AWS Lake Formation, and create the rules dataset in Amazon QuickSight for the saas_sales table.

Extract and transform data filters and permissions from AWS Lake Formation using a Lambda function

In AWS Lake Formation, data filters are created for each table. There can be many tables in AWS Lake Formation. However, for a team or a project, there are only a specific set of tables that the BI developer is interested in. Therefore, choose a list of tables to track and update the data filters for. In a batch process, for each table in AWS Lake Formation, extract the data filter definitions and write them into Amazon S3 using AWS Lake Formation and Amazon S3 APIs.

We use the following AWS Lake Formation APIs to extract the data filter details and permissions:

  • ListDataCellFilters – This API is used to list all the data filters in each table that is required for the project
  • ListPermissions – This API is used to retrieve the permissions for each of the data filters extracted using the ListDataCellFilters API

The Lambda function covers three parts of the solution:

  • Extract the data filters and permissions to data filters for tables of interest from AWS Lake Formation
  • Transform the data filters and permission into a format usable in Amazon QuickSight
  • Persist the transformed data

Complete the following steps to create an AWS Lambda function:

  1. On the Lambda console, create a function called Lake_Formation_QuickSight_RLS. Use Python 3.12 as the runtime and create a new role for execution.
  2. Configure Lambda function timeout to 2 minutes. This can vary depending on the number of tables to be parsed and the number of data filters to be transformed.
  3. Attach the following permissions to the Lambda execution role:
    {
    "Version": "2012-10-17",
    "Statement": [
    {
    "Sid": "VisualEditor0",
    "Effect": "Allow",
    "Action": [
    "lakeformation:ListDataCellsFilter",
    "lakeformation:ListPermissions"
    ],
    "Resource": "*"
    },
    {
    "Sid": "VisualEditor1",
    "Effect": "Allow",
    "Action": "s3:PutObject",
    "Resource": "arn:aws:s3:::<bucket_used_for_storage>/*"
    }
    ]
    }

  4. Set the following environment variables for the Lambda function:

    Name Value
    S3Bucket Value of the S3 bucket where the output files will be stored
    tablesToTrack List of tables to track as JSON converted to string
    Tmp /tmp

The Lambda function gets the list of tables and S3 bucket details from the environment variables. The list of tables is given as a JSON array converted to string. The JSON format is shown in the following code. The values for catalogId, DatabaseName, and Name can be fetched from the AWS Lake Formation console.

[
{
"CatalogId": "String",
"DatabaseName": "String",
"Name": "String"
}
]
  1. Add a folder named tmp.
  2. Download the zip file Lake_Formation_QuickSight_RLS.zip.
    Note: This is sample code for non-production usage. You should work with your security and legal teams to meet your organizational security, regulatory, and compliance requirements before deployment.
  3. For the Lambda function code, upload the downloaded .zip file to the Lambda function, on the Code tab.
  4. Provide necessary access to the execution role in AWS Lake Formation. Although the AWS Identity and Access Management (IAM) permissions are given to the Lambda execution role, explicit permission has to be given to the role in AWS Lake Formation for the Lambda function to get the details about the data filters. Therefore, you have to explicitly grant access to the execution role to limit the Lambda role to read-only admin. For more details, see Viewing data filters.

In the following sections, we explain what the Lambda function code does in more detail.

Extract data filters and permissions for data filters and tables in AWS Lake Formation

The main flow of the code takes the list of tables as input and extracts table and data filter permissions and data filter rules. The approach here is to get the permissions for the entire table and also for the data filters applied to the table. This way, both full access (table level) and partial access (data filter) can be extracted.

...
....
tablesToTrack= json.loads(os.environ["tablesToTrack"])
lf_client = boto3.client('lakeformation')
# For each table in the list get the data filter rules attached to the table.
for table in tablesToTrack:
df_response= lf_client.list_data_cells_filter(
Table= table
)
d_filters += df_response["DataCellsFilters"]

# Also, for each table in the list get the list of permissions at table level.
# This determines who has access to all rows in the table.
tresponse=lf_client.list_permissions(
Resource= {
"Table": table
}
)

d_permissions += tresponse["PrincipalResourcePermissions"]
transformDataFilterRules(d_filters)
# For each data filters fetched above, get the permissions.
# This determines the row level security for the tables.
for filter in d_filters:
p_response=lf_client.list_permissions(
Resource= {

"DataCellsFilter": {
"DatabaseName": filter ["DatabaseName"],
"Name": filter["Name"],
"TableCatalogId": filter["TableCatalogId"],
"TableName": filter["TableName"]
}

}
)
d_permissions += p_response["PrincipalResourcePermissions"]

transformFilterandTablePermissions(d_permissions)

Transform data filter definitions in to a format usable in Amazon QuickSight

The extracted permissions and filters are transformed to create a rules dataset in Amazon QuickSight. There are different ways to define data filters. The following figure illustrates some of the example transformations.

The function transformDataFilterRules in the following code can transform some of the OR and AND conditions into Amazon QuickSight acceptable format. The following are the details available in the transformed format:

  • Lake Formation catalog ID
  • Lake Formation database name
  • Lake Formation table name
  • Lake Formation data filter name
  • List of columns from all the tables provided in the input for which the data filter rules are defined

See the following code:

def transformDataFilterRules(rules):
global complete_transformed_filter_rules
transformed_filter_rules = []
filter_to_extract=[]
complete_transformed_filter_rules = []
col_headers=[]
col_headers.append("catalog")
col_headers.append("database")
col_headers.append("table")
col_headers.append("filter")

for rule in rules:
print(rule)
catalog=rule["TableCatalogId"]
database = rule["DatabaseName"]
table = rule["TableName"]
filter = rule["Name"]
row=[]
row.append(catalog)
row.append(database)
row.append(table)
row.append(filter)
logger.info(f"row==={row}")

f_conditions = re.split(' OR | or | and | AND ' , rule["RowFilter"]["FilterExpression"])

for f_condition in f_conditions:
logger.info(f"f_condition={f_condition}")
f_condition = f_condition.replace("(","")
f_condition = f_condition.replace(")","")
filter_rule_column= f_condition.split("=")
if len(filter_rule_column)>1:
filter_rule_column[0] = filter_rule_column[0].strip()
if not filter_rule_column[0].strip() in col_headers:
col_headers.append(filter_rule_column[0].strip())
i= col_headers.index(filter_rule_column[0].strip())
j= i- (len(row)-1)
if j>0:
for x in range(1, j):
row.append("")
logger.info(f"i={i} j={j} {filter_rule_column[1]}")
row.insert(i, filter_rule_column[1].replace("'",""))
print(row)
transformed_filter_rules.append(','.join(row))

row=[]
row.append(catalog)
row.append(database)
row.append(table)
row.append(filter)
max_columns = len(col_headers)
complete_transformed_filter_rules=[]
for rule in transformed_filter_rules:
r = rule.split(",")
to_fill = max_columns - len(r)
if to_fill>0:
for x in range(1, to_fill+1):
r.append("")
complete_transformed_filter_rules.append(','.join(r))

complete_transformed_filter_rules.insert(0,','.join(col_headers))

The following figure is an example of the transformed file. The file contains the columns for both tables. When creating a rules dataset for a specific table, the records are filtered for that table pulled into Amazon QuickSight.

The function transformFilterandTablePermissions in the following code snippet combines and transforms the table and data filter permissions into a flat structure that contains the following columns:

  • Amazon QuickSight group ARN
  • Lake Formation catalog ID
  • Lake Formation database name
  • Lake Formation table name
  • Lake Formation data filter name

See the following code:

def transformFilterandTablePermissions(permissions):
    global transformed_table_permissions,transformed_filter_permissions
    # Read and set table level access
    transformed_table_permissions = []
    transformed_filter_permissions = []
    transformed_filter_permissions.insert(0,"group,catalog,database,table,filter")
    transformed_table_permissions.insert(0,"group,catalog,database,table")
    
    for permission in permissions:
    group=""
    database=""
    table =""
    catalog=""
    
    p= permission["Permissions"]
    
    if "DESCRIBE" in p or "SELECT" in p:
    
    group = permission["Principal"]["DataLakePrincipalIdentifier"]
    if "Database" in permission["Resource"]:
    catalog=permission["Resource"]["Database"]["CatalogId"]
    database=permission["Resource"]["Database"]["Name"]
    table = "*"
    transformed_table_permissions.append(group + "," + catalog+ "," + database + "," + table)
    transformed_filter_permissions.append(group+"," +catalog + ","+ database + ","+ table)
    elif "TableWithColumns" in  permission["Resource"]  or "Table" in permission["Resource"]:
    if "TableWithColumns" in  permission["Resource"]:
    catalog=permission["Resource"]["TableWithColumns"]["CatalogId"]
    database = permission["Resource"]["TableWithColumns"]["DatabaseName"]
    table = permission["Resource"]["TableWithColumns"]["Name"]
    elif "Table" in  permission["Resource"]:
    catalog=permission["Resource"]["Table"]["CatalogId"]
    database = permission["Resource"]["Table"]["DatabaseName"]
    table = permission["Resource"]["Table"]["Name"]
    transformed_table_permissions.append( group + "," + catalog + "," + database + "," + table)
    transformed_filter_permissions.append(group+"," +catalog + ","+ database + ","+ table)
    elif "DataCellsFilter" in permission["Resource"]:
    catalog=permission["Resource"]["DataCellsFilter"]["TableCatalogId"]
    database = permission["Resource"]["DataCellsFilter"]["DatabaseName"]
    table = permission["Resource"]["DataCellsFilter"]["TableName"]
    filter = permission["Resource"]["DataCellsFilter"]["Name"]
    transformed_filter_permissions.append(group+"," +catalog + ","+ database + ","+ table+ ","+ filter)

The following figure is an example of the extracted data filter and table permissions. AWS Lake Formation can have data filters applied to any principal. However, we focus on the Amazon QuickSight principals:

  • The QuickSight_Authors ARN has full access to two tables. This is determined by transforming the table-level permissions in addition to the data filter permissions.
  • The QuickSight_Readers ARN has limited access based on filter conditions.

Store the transformed rules and permissions in two separate files in Amazon S3

The transformed rules and permissions are then persisted in a data store. In this solution, the transformed rules are written to an Amazon S3 location in CSV format. The name of the files created by the Lambda function are:

  • transformed_filter_permissions.csv
  • transformed_filter_rules.csv

See the following code:

with open("/tmp/transformed_table_permissions.csv", "w") as txt_file:
for line in transformed_table_permissions:
txt_file.write(line + "\n") # works with any number of elements in a line
txt_file.close()
s3 = boto3.resource('s3')
s3.meta.client.upload_file(Filename = "/tmp/transformed_table_permissions.csv", Bucket= os.environ['S3Bucket'], Key = "table-permissions/transformed_table_permissions.csv")

with open("/tmp/transformed_filter_permissions.csv", "w") as txt_file:
for line in transformed_filter_permissions:
txt_file.write(line + "\n") # works with any number of elements in a line
txt_file.close()

s3.meta.client.upload_file(Filename = "/tmp/transformed_filter_permissions.csv", Bucket= os.environ['S3Bucket'], Key = "filter-permissions/transformed_filter_permissions.csv")

with open("/tmp/transformed_filter_rules.csv", "w") as txt_file:
for line in complete_transformed_filter_rules:
txt_file.write(line + "\n") # works with any number of elements in a line
txt_file.close()

s3.meta.client.upload_file(Filename = "/tmp/transformed_filter_rules.csv", Bucket= os.environ['S3Bucket'], Key = "filter-rules/transformed_filter_rules.csv")

Create a rules dataset in Amazon QuickSight

In this section, we walk through the steps to create a rules dataset in Amazon QuickSight.

Create a table in Lake formation for the files

The first step is to create a table in AWS Lake Formation for the two files, transformed_filter_permissions.csv and transformed_filter_rules.csv.

Although you can directly use an Amazon S3 connector in Amazon QuickSight, creating a table and making the rules dataset using an Athena connector gives flexibility in writing custom SQL and using direct query. For the steps to bring an Amazon S3 location into AWS Lake Formation, see Creating tables.

For this post, the tables for the files are created in a separate database called quicksight_lf_transformation.

Grant permission for the tables to the QuickSight_Authors group

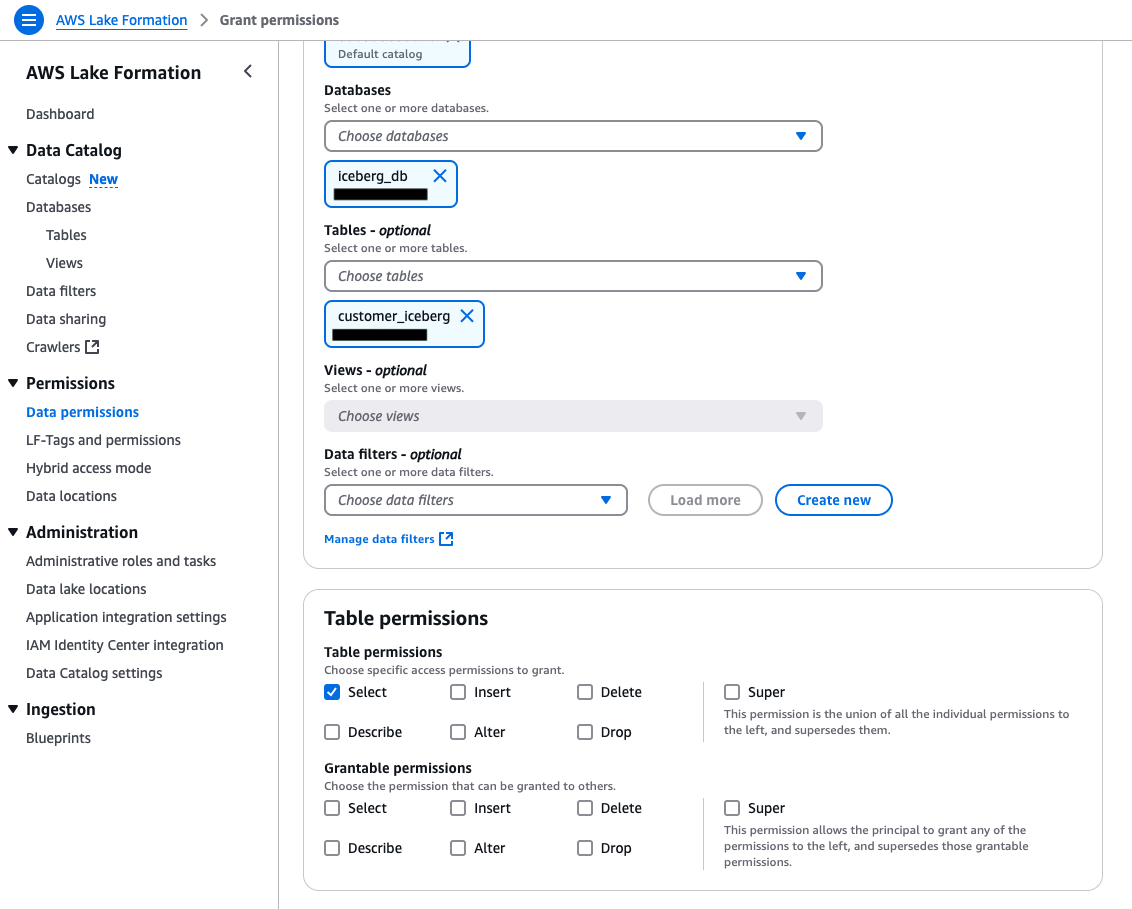
Grant permission in AWS Lake Formation for the two tables to the QuickSight_Authors group. This is essential for Amazon QuickSight authors to create a rules dataset in Amazon QuickSight. The following screenshot shows the permission details.

Create a rules dataset in Amazon QuickSight

Amazon QuickSight supports both user-level and group-level RLS. In this post, we use groups to enable RLS. To create the rules dataset, you first join the filter permissions table with the filter rules table on the columns catalog, database, table, and filter. Then you can filter the permissions to include the Amazon QuickSight principals, and include only the columns required for the dataset. The objective in this solution is to build a rules dataset for the saas_sales table.

Complete the following steps:

  1. On the Amazon QuickSight console, create a new Athena dataset.
  2. Specify the following:
    1. For Catalog, choose AWSDataCatalog.
    2. For Database, choose quicksight_lf_transformation.
    3. For Table, choose filter_permissions.
  3. Choose Edit/Preview data.
  4. Choose Add data.
  5. Choose Add source.
  6. Select Athena.
  7. Specify the following:
    1. For Catalog, choose AWSDataCatalog.
    2. For Database, choose quicksight_lf_transformation.
    3. For Table, choose filter_rules.

  8. Join the permissions table with the data filter rules table on the catalog, database, table and filter columns.
  9. Rename the column group as GroupArn. This needs to be done before filter is applied.
  10. Filter the data where column table equals saas_sales.
  11. Filter the data where column group is also filtered for values starting with arn:aws:quicksight (Amazon QuickSight principals).
  12. Exclude fields that are not part of the saas_sales table.
  13. Change Query mode to SPICE.
  14. Publish the dataset.

If your organization has a mapping of other principals to a Amazon QuickSight group or user, you can apply that mapping before joining the tables.

You can also write the following custom SQL to achieve the same result:

SELECT a."group" as GroupArn, segment FROM "QuickSight_lf_transformation"."filter_permissions" as a
left join
"QuickSight_lf_transformation"."filter_rules" as b
on
a.catalog = b.catalog and
a.database = b.database and
a."table" = b."table" and
a.filter = b.filter
where a."table" = 'saas_sales'
and a."group" like 'arn:aws:quicksight%'

  1. Name the dataset LakeFormationRLSDataSet and publish the dataset.

Test the row-level security

Now you’re ready to test the row-level security by publishing a dashboard as a user in the QuickSight_Authors group and then viewing the dashboard as a user in the QuickSight_Readers group.

Publish a dashboard as a QuickSight_Authors group user

As an author who belongs to the QuickSight_Authors group, the user will be able to see the saas_sales table in the Athena connector and all the data in the table. As shown in this section, all three segments are visible for the author when creating an analysis and viewing the published dashboard.

  1. Create a dataset by pulling data from the saas_sales table using the Athena connector.
  2. Attach LakeFormationRLSDataSet as the RLS dataset for the saas_sales dataset. For instructions, see Using row-level security with user-based rules to restrict access to a dataset.
  3. Create an analysis using the saas_sales dataset as an author who belongs to the QuickSight_Authors group.
  4. Publish the dashboard.
  5. Share the dashboard with the group QuickSight_Readers.

View the dashboard as a QuickSight_Readers group user

Complete the following steps to view the dashboard as a QuickSight_Readers group user:

  1. Log into Amazon QuickSight as a reader who belongs to the QuickSight_Readers group.

The user will be able to see only the segment Enterprise.

  1. Now, change the RLS in AWS Lake Formation, and set the segment to be SMB for the QuickSightReaderFilter.
  2. Run the Lambda function to export and transform the new data filter rules.
  3. Refresh the SPICE dataset LakeFormationRLSDataSet in Amazon QuickSight.
  4. When the refresh is complete, refresh the dashboard in the reader login.

Now the reader user will see SMB data.

Cleanup

Amazon QuickSight resources

  1. Delete the Amazon QuickSight dashboard and analysis created
  2. Delete the datasets saas_sales and LakeFormationRulesDataSet
  3. Delete the Athena data source
  4. Delete the QuickSight groups using the DeleteGroup API

AWS Lake Formation resources

  1. Delete the database quicksight_lf transformation created in AWS Lake Formation
  2. Revoke permission given to the Lambda execution role
  3. Delete the saas_sales table and data filters created
  4. If you have used Glue crawler to create the tables in AWS Lake Formation, remove the Glue crawler as well

Compute resources

  1. Delete the AWS Lambda function created
  2. Delete the AWS Lambda execution role associated with the lambda

Storage resources

  1. Empty the content of the Amazon S3 bucket created for this solution
  2. Delete the Amazon S3 bucket

Conclusion

This post explained how to replicate row-level security in AWS Lake Formation automatically in Amazon QuickSight. This makes sure that the SPICE dataset in QuickSight can use row-level access defined in Lake Formation.

This solution can also be extended for other data sources. The logic to programmatically extract the entitlements from the source and transform them into Amazon QuickSight format will vary by source. After the extract and transform are in place, it can scale to multiple teams in the organization. Although this post laid out a basic approach, the automation has to be either scheduled to run periodically or triggered based on events like data filters change or grant or revoke of AWS Lake Formation permissions to make sure that the entitlements remain in sync between AWS Lake Formation and Amazon QuickSight.

Try out this solution for your own use case, and share your feedback in the comments.


About the Authors

Vetri Natarajan is a Specialist Solutions Architect for Amazon QuickSight. Vetri has 15 years of experience implementing enterprise business intelligence (BI) solutions and greenfield data products. Vetri specializes in integration of BI solutions with business applications and enable data-driven decisions.

Ismael Murillo is a Solutions Architect for Amazon QuickSight. Before joining AWS, Ismael worked in Amazon Logistics (AMZL) with delivery station management, delivery service providers, and our customer actively in the field. Ismael focused on last mile delivery and delivery success. He designed and implemented many innovative solutions to help reduce cost, influence delivery success. He is also a United States Army Veteran, where he served for eleven years.

AWS Lambda introduces tiered pricing for Amazon CloudWatch logs and additional logging destinations

Post Syndicated from Shridhar Pandey original https://aws.amazon.com/blogs/compute/aws-lambda-introduces-tiered-pricing-for-amazon-cloudwatch-logs-and-additional-logging-destinations/

Effective logging is an important part of an observability strategy when building serverless applications using AWS Lambda.

Lambda automatically captures and sends logs to Amazon CloudWatch Logs. This allows you to focus on building application logic rather than setting up logging infrastructure and allows operators to troubleshoot failures and performance issues more easily.

On May 1st, 2025, AWS announced changes to Lambda logging, which can reduce Lambda CloudWatch logging costs and make it easier and more cost-effective to use a wider range of monitoring tools. Lambda logs are now available at volume-based tiered pricing when using CloudWatch Logs Standard and Infrequent Access log classes. When generating Lambda logs at scale, you can expect an immediate cost reduction under this new pricing model. Lambda also now supports Amazon S3 and Amazon Data Firehose as additional destinations for Lambda logs, in addition to CloudWatch Logs. Lambda logs sent to S3 and Firehose are also available at volume-based tiered pricing.

This blog post covers some recent Lambda logging enhancements and describes how this change delivers a simpler, more cost-effective logging experience for Lambda.

Overview

Logging provides developers and operators with valuable data for debugging and troubleshooting application behavior, performance issues, and potential failures. It becomes even more important for serverless applications built using Lambda because of the ephemeral and stateless nature of the Lambda execution environment. Lambda’s built-in integration with CloudWatch Logs ensures that logs for every function invocation are readily available for analysis. The captured log data includes application logs generated by your Lambda function code and system logs generated by the Lambda service while running your function code. CloudWatch Logs allows you to search, filter, and analyze log data to troubleshoot issues, track metrics, and set up alerts.

Logging requirements evolve as serverless applications grow in complexity and scale, sometimes spanning hundreds or thousands of Lambda functions which generate substantial log volumes. Organizations need sophisticated logging solutions that can handle this scale while remaining cost-effective. Some scenarios—such as monitoring critical business transactions—demand real-time log analysis, while others focus on after-the-fact forensic analysis. Debug logs from development and staging environments often need high granularity, whereas you may want lower verbosity in production logs to improve the signal-to-noise ratio.

Recent Lambda logging enhancements

In recent years, Lambda and CloudWatch Logs have expanded Lambda’s logging capabilities to meet the evolving needs of serverless applications. These capabilities provide deeper insights, greater control, and more cost-effective solutions to capture, process, and consume logs to enhancing the serverless observability experience. Lambda advanced logging controls gives developers control over log generation and content. These controls allow you to capture Lambda logs in JSON structured format. You don’t have to use logging libraries and customize log levels (INFO, DEBUG, WARN, ERROR) separately for application and system logs. This helps reduce logging costs by ensuring only necessary logs are generated while maintaining appropriate visibility across different environments. For example, you can set verbose DEBUG level logging in development environments while limiting production logging to ERROR level to improve the signal-to-noise ratio and control costs.

The Infrequent Access log class for CloudWatch Logs introduced a cost-effective solution for logs that need retention but are accessed less frequently. Infrequent Access is 50% lower per GB ingestion price than the Standard log class This tailored set of capabilities allows you to reduce your logging costs while maintaining access to historical data for compliance, audit purposes, or forensic analysis.

CloudWatch Logs Live Tail is an interactive, real-time log streaming and analytics capability. Live Tail streamlines debugging and monitoring workflows; it allows you to observe log output as functions execute without navigating away from the Lambda console. This makes it easier to identify and diagnose issues during development and troubleshooting. Logs Live Tail is also available in Visual Code IDE.

Tiered pricing for Lambda logs in CloudWatch Logs

Starting today, Lambda logs sent to CloudWatch Logs are classed as Vended Logs, which are logs from specific AWS services that are available at volume tiered pricing. This replaces the previous flat rate model when using CloudWatch Logs Standard log class. For example, in the US East (N. Virginia) AWS Region, you were charged at $0.50 per GB when using Standard log class for your Lambda logs. Under the new pricing model, you are charged for sending your Lambda logs to CloudWatch Logs starting at $0.50 per GB for initial usage. As log volume increases, the price per GB automatically decreases through multiple tiers, reaching rates as low as $0.05 per GB in the lowest tier. This pricing change applies automatically to all Lambda logs sent to CloudWatch Logs, requiring no code or configuration changes from you.

Data Ingested CloudWatch Logs Standard CloudWatch Logs Infrequent Access
First 10 TB per month $0.50 per GB $0.25 per GB
Next 20 TB per month $0.25 per GB $0.15 per GB
Next 20 TB per month $0.10 per GB $0.075 per GB
Over 50 TB per month $0.05 per GB $0.05 per GB

Table 1: Tiered pricing for Lambda logs in CloudWatch Logs in US East (N. Virginia) Region

When generating Lambda logs at scale, you will see an immediate cost reduction under this new pricing model. For example, if you generate 60 TB of Lambda logs monthly in CloudWatch Logs, costs would decrease by 58% (from $30,000 to $12,500). The pricing tiers scale with your logging volume, ensuring that cost benefits increase as your application grows. This allows you to maintain comprehensive logging practices that previously may have been cost-prohibitive. Vended logs tiered pricing is applied on all vended logs ingested to CloudWatch and not tiered per service.

When ingesting other vended logs, such as Amazon Virtual Private Cloud flow logs and Amazon Route 53 resolver query logs, you will see larger discounts as the tiering is applied at a consolidated log ingestion volume.

New Lambda logging destinations: Amazon S3 and Amazon Data Firehose

Starting today, Lambda also supports Amazon S3 and Amazon Data Firehose as destinations for Lambda logs, in addition to CloudWatch Logs. When using S3 or Firehose as a destination, logging costs start at $0.25 per GB. The tiered pricing also applies, with rates reducing to as low as $0.05 per GB in the lowest tier. This tiering is also applied at a consolidated log ingestion volume.

Data Ingested Delivery Cost to Amazon S3 Delivery Cost to Amazon Data Firehose
First 10TB per month $0.25 per GB $0.25 per GB
Next 20TB per month $0.15 per GB $0.15 per GB
Next 20TB per month $0.075 per GB $0.075 per GB
Over 50TB per month $0.05 per GB $0.05 per GB

Table 2:Tiered pricing for Lambda logs delivery to Amazon S3 and Amazon Data Firehose in US East (N. Virginia) Region

Direct delivery of Lambda logs to S3 provides enhanced flexibility in log management. Support for Firehose streamlines Lambda log delivery to additional destinations such as Amazon OpenSearch Service, HTTP endpoints, and third-party observability providers. This matches the established log delivery pattern used with other AWS compute services such as Amazon Elastic Container Service (Amazon ECS) and Amazon Elastic Compute Cloud (Amazon EC2).

This new capability provides significant cost benefits and streamlines log delivery to additional logging destinations, making it easier to use a wider range of monitoring tools (including CloudWatch) when building serverless applications using Lambda.

New Lambda logging destinations in action

All new and existing Lambda functions have CloudWatch Logs as the default logging destination, with S3 and Firehose as alternative choices. When you select S3 or Firehose as your logging destination, Lambda sends logs to the selected destination via a new CloudWatch Logs Delivery log class. This log class enables efficient routing but doesn’t support CloudWatch Logs Standard log class features, such as Logs Insights and Live Tail.

To set up S3 or Firehose as the destination for your Lambda logs in the Lambda console:

  1. Navigate to the Lambda console, and select or create a function to set up an S3 or Firehose logging destination.
  2. In the Configuration tab, select Monitoring and operations tools on the left pane.
  3. Select Edit in the Logging configuration. This opens the Edit logging configuration page.

    Figure 1. Edit logging configuration in Lambda console

    Figure 1. Edit logging configuration in Lambda console

  4. In the Log destination section, select Amazon S3 or Amazon Data Firehose. Amazon CloudWatch Logs is the default selection.

    Figure 2. Select log destination in the Edit logging configuration page

    Figure 2. Select log destination in the Edit logging configuration page

  5. Under CloudWatch delivery log group, choose Create new log group or Existing log group.
  6. To create a new delivery log group to send logs to S3, enter a log group name and specify the destination S3 bucket. Provide an AWS Identity and Access Management (IAM) role for CloudWatch Logs to deliver logs to S3.
    Follow similar steps to send logs to a Firehose stream.

    Figure 3. Create new CloudWatch delivery log group for S3

    Figure 3. Create new CloudWatch delivery log group for S3

  7. To use an existing delivery log group, select one from the Delivery log group. The selected delivery log group must have a configured destination (S3 or Firehose) and match the destination you selected.

    Figure 4. Select existing CloudWatch delivery log group for Firehose

    Figure 4. Select existing CloudWatch delivery log group for Firehose

Advanced logging controls are also available for S3 and Firehose destinations. These controls include JSON structured format selection and log level filters for both application and system logs. This gives you enhanced log management controls for easier search, filter, and analysis. You can also use AWS Command Line Interface (AWS CLI) and infrastructure as code (IaC) tools such as AWS CloudFormation and AWS Cloud Development Kit (AWS CDK) to set up Lambda logs delivery to S3 and Firehose.

Best practices

To get the most out of the changes announced today, ensure that your logging strategy is closely aligned with the requirements of your workload. For example, consider sending critical production logs to CloudWatch Logs to take advantage of its advanced real-time analytics and alerting features. You now automatically benefit from volume-based discounts through tiered pricing in CloudWatch Logs for high-volume logging scenarios. For logs that need long-term retention for historical analysis, you can use S3’s storage classes to further reduce costs. When using your existing or third-party monitoring tools, direct integration through Firehose eliminates the need for custom forwarding solutions and associated costs.

Logging cost optimization extends beyond destination selection. Monitor log volumes regularly to understand the impact of pricing tiers. Implement appropriate retention policies to prevent unnecessary storage of old logs and log sampling for high-volume debug logs. Consider using different logging strategies across development, staging, and production environments to balance observability needs with cost efficiency.

Conclusion

Tiered pricing for Lambda logs in CloudWatch Logs and support for S3 and Firehose as additional logging destinations improves Lambda application observability. You can now manage logging costs at scale and expand Lambda monitoring solutions through cost-effective, easy-to-configure integrations. Whether you’re building new serverless applications or optimizing existing ones, these enhancements help you implement comprehensive logging strategies that scale cost-effectively with your workload.

The new features announced today are available in all commercial AWS Regions where Lambda and CloudWatch Logs are available. Support for configuring log delivery to S3 and Firehose in the Lambda console is available in US East (Ohio), US East (N. Virginia), US West (Oregon), and Europe (Ireland) Regions, with additional Regions coming soon. Review the Lambda documentation and CloudWatch Logs documentation to learn more about these features and how to use them. Review the CloudWatch pricing page to learn more about how these features are priced.

For more serverless learning resources, visit Serverless Land.

Build end-to-end Apache Spark pipelines with Amazon MWAA, Batch Processing Gateway, and Amazon EMR on EKS clusters

Post Syndicated from Avinash Desireddy original https://aws.amazon.com/blogs/big-data/build-end-to-end-apache-spark-pipelines-with-amazon-mwaa-batch-processing-gateway-and-amazon-emr-on-eks-clusters/

Apache Spark workloads running on Amazon EMR on EKS form the foundation of many modern data platforms. EMR on EKS offers benefits by providing managed Spark that integrates seamlessly with other AWS services and your organization’s existing Kubernetes-based deployment patterns.

Data platforms processing large-scale data volumes often require multiple EMR on EKS clusters. In the post Use Batch Processing Gateway to automate job management in multi-cluster Amazon EMR on EKS environments, we introduced Batch Processing Gateway (BPG) as a solution for managing Spark workloads across these clusters. Although BPG provides foundational functionality to distribute workloads and support routing for Spark jobs in multi-cluster environments, enterprise data platforms require additional features for a comprehensive data processing pipeline.

This post shows how to enhance the multi-cluster solution by integrating Amazon Managed Workflows for Apache Airflow (Amazon MWAA) with BPG. By using Amazon MWAA, we add job scheduling and orchestration capabilities, enabling you to build a comprehensive end-to-end Spark-based data processing pipeline.

Overview of solution

Consider HealthTech Analytics, a healthcare analytics company managing two distinct data processing workloads. Their Clinical Insights Data Science team processes sensitive patient outcome data requiring HIPAA compliance and dedicated resources, and their Digital Analytics team handles website interaction data with more flexible requirements. As their operation grows, they face increasing challenges in managing these diverse workloads efficiently.

The company needs to maintain strict separation between protected health information (PHI) and non-PHI data processing, while also addressing different cost center requirements. The Clinical Insights Data Science team runs critical end-of-day batch processes that need guaranteed resources, whereas the Digital Analytics team can use cost-optimized spot instances for their variable workloads. Additionally, data scientists from both teams require environments for experimentation and prototyping as needed.

This scenario presents an ideal use case for implementing a data pipeline using Amazon MWAA, BPG, and multiple EMR on EKS clusters. The solution needs to route different Spark workloads to appropriate clusters based on security requirements and cost profiles, while maintaining the necessary isolation and compliance controls. To effectively manage such an environment, we need a solution that maintains clean separation between application and infrastructure management concerns and stitching together multiple components into a robust pipeline.

Our solution consists of integrating Amazon MWAA with BPG through an Airflow custom operator for BPG called BPGOperator. This operator encapsulates the infrastructure management logic needed to interact with BPG. BPGOperator provides a clean interface for job submission through Amazon MWAA. When executed, the operator communicates with BPG, which then routes the Spark workloads to available EMR on EKS clusters based on predefined routing rules.

The following architecture diagram illustrates the components and their interactions.

Image showing the end to end architecture for end-to-end pipeline

The solution works through the following steps:

  • Amazon MWAA executes scheduled DAGs using BPGOperator. Data engineers create DAGs using this operator, requiring only the Spark application configuration file and basic scheduling parameters.
  • BPGOperator authenticates and submits jobs to the BPG submit endpoint POST:/apiv2/spark. It handles all HTTP communication details, manages authentication tokens, and provides secure transmission of job configurations.
  • BPG routes submitted jobs to EMR on EKS clusters based on predefined routing rules. These routing rules are managed centrally through BPG configuration, allowing rules-based distribution of workloads across multiple clusters.
  • BPGOperator monitors job status, captures logs, and handles execution retries. It polls the BPG job status endpoint GET:/apiv2/spark/{subID}/status and streams logs to Airflow by polling the GET:/apiv2/log endpoint every second. The BPG log endpoint retrieves the most current log information directly from the Spark Driver Pod.
  • The DAG execution progresses to subsequent tasks based on job completion status and defined dependencies. BPGOperator communicates the job status through Airflow’s built-in task communication system, enabling complex workflow orchestration.

Refer to the BPG REST API interface documentation for additional details.

This architecture provides several key benefits:

  • Separation of responsibilities – Data Engineering and Platform Engineering teams in enterprise organizations typically maintain distinct responsibilities. The modular design in this solution enables platform engineers to configure BPGOperator and manage EMR on EKS clusters, while data engineers maintain DAGs.
  • Centralized code management – BPGOperator encapsulates all core functionalities required for Amazon MWAA DAGs to submit Spark jobs through BPG into a single, reusable Python module. This centralization minimizes code duplication across DAGs and improves maintainability by providing a standardized interface for job submissions.

Airflow custom operator for BPG

An Airflow Operator is a template for a predefined Task that you can define declaratively inside your DAGs. Airflow provides multiple built-in operators such as BashOperator, which executes bash commands, PythonOperator, which executes Python functions, and EmrContainerOperator, which submits new jobs to an EMR on EKS cluster. However, no built-in operators exist to implement all the steps required for the Amazon MWAA integration with BPG.

Airflow allows you to create new operators to suit your specific requirements. This operator type is known as a custom operator. A custom operator encapsulates the custom infrastructure-related logic in a single, maintainable component. Custom operators are created by extending the airflow.models.baseoperator.BaseOperator class. We have developed and open sourced an Airflow custom operator for BPG called BPGOperator, which implements the necessary steps to provide a seamless integration of Amazon MWAA with BPG.

The following class diagram provides a detailed view of the BPGOperator implementation.

Image showing class diagram for BPGOperator implementation

When a DAG includes a BPGOperator task, the Amazon MWAA instance triggers the operator to send a job request to BPG. The operator typically performs the following steps:

  • Initialize job – BPGOperator prepares the job payload, including input parameters, configurations, connection details, and other metadata required by BPG.
  • Submit job – BPGOperator handles HTTP POST requests to submit jobs to BPG endpoints with the provided configurations.
  • Monitor job execution – BPGOperator checks the job status, polling BPG until the job completes successfully or fails. The monitoring process includes handling various job states, managing timeout scenarios, and responding to errors that occur during job execution.
  • Handle job completion – Upon completion, BPGOperator captures the job results, logs relevant details, and can trigger downstream tasks based on the execution outcome.

The following sequence diagram illustrates the interaction flow between the Airflow DAG, BPGOperator, and BPG.

Image showing sequence diagram for the interaction between the Airflow DAG, BPGOperator, and BPG.

Deploying the solution

In the remainder of this post, you will implement the end-to-end pipeline to run Spark jobs on multiple EMR on EKS clusters. You will begin by deploying the common components that serve as the foundation for building the pipelines. Next, you will deploy and configure BPG on an EKS cluster, followed by deploying and configuring BPGOperator on Amazon MWAA. Finally, you will execute Spark jobs on multiple EMR on EKS clusters from Amazon MWAA.

To streamline the setup process, we’ve automated the deployment of all infrastructure components required for this post, so you can focus on the essential aspects of job submission to build an end-to-end pipeline. We provide detailed information to help you understand each step, simplifying the setup while preserving the learning experience.

To showcase the solution, you will create three clusters and an Amazon MWAA environment:

  • Two EMR on EKS clusters: analytics-cluster and datascience-cluster
  • An EKS cluster: gateway-cluster
  • An Amazon MWAA environment: airflow-environment

analytics-cluster and datascience-cluster serve as data processing clusters that run Spark workloads, gateway-cluster hosts BPG, and airflow-environment hosts Airflow for job orchestration and scheduling.

You can find the code base in the GitHub repo.

Prerequisites

Before you deploy this solution, make sure that the following prerequisites are in place:

Set up common infrastructure

This step handles the setup of networking infrastructure, including virtual private cloud (VPC) and subnets, along with the configuration of AWS Identity and Access Management (IAM) roles, Amazon Simple Storage Service (Amazon S3) storage, Amazon Elastic Container Registry (Amazon ECR) repository for BPG images, Amazon Aurora PostgreSQL-Compatible Edition database, Amazon MWAA environment, and both EKS and EMR on EKS clusters with a preconfigured Spark operator. With this infrastructure automatically provisioned, you can concentrate on the subsequent steps without getting caught up in basic setup tasks.

  1. Clone the repository to your local machine and set the two environment variables. Replace <AWS_REGION> with the AWS Region where you want to deploy these resources.
    git clone https://github.com/aws-samples/sample-mwaa-bpg-emr-on-eks-spark-pipeline.git
    cd sample-mwaa-bpg-emr-on-eks-spark-pipeline
    			
    export REPO_DIR=$(pwd)
    export AWS_REGION=<AWS_REGION>

  2. Execute the following script to create the common infrastructure:
    cd ${REPO_DIR}/infra
    ./setup.sh

  3. To verify successful infrastructure deployment, navigate to the AWS CloudFormation console, open your stack, and check the Events, Resources, and Outputs tabs for completion status, details, and list of resources created.

You have completed the setup of the common components that serve as the foundation for rest of the implementation.

Set up Batch Processing Gateway

This section builds the Docker image for BPG, deploys the helm chart on the gateway-cluster EKS cluster, and exposes the BPG endpoint using Kubernetes service of type LoadBalancer. Complete the following steps:

  1. Deploy BPG on the gateway-cluster EKS cluster:
    cd ${REPO_DIR}/infra/bpg
    ./configure_bpg.sh

  2. Verify the deployment by listing the pods and viewing the pod logs:
    kubectl get pods --namespace bpg
    kubectl logs <BPG-PODNAME> --namespace bpg

    Review the logs and confirm there are no errors or exceptions.

  3. Exec into the BPG pod and verify the health check:
    kubectl exec -it <BPG-PODNAME> -n bpg -- bash
    curl -u admin:admin localhost:8080/skatev2/healthcheck/status

    The healthcheck API should return a successful response of {"status":"OK"}, confirming successful deployment of BPG on the gateway-cluster EKS cluster.

We have successfully configured BPG on gateway-cluster and set up EMR on EKS for both datascience-cluster and analytics-cluster. This is where we left off in the previous blog post. In the next steps, we will configure Amazon MWAA with BPGOperator, and then write and submit DAGs to demonstrate an end-to-end Spark-based data pipeline.

Configure the Airflow operator for BPG on Amazon MWAA

This section configures the BPGOperator plugin on the Amazon MWAA environment airflow-environment. Complete the following steps:

  1. Configure BPGOperator on Amazon MWAA:
    cd ${REPO_DIR}/bpg_operator
    ./configure_bpg_operator.sh

  2. On the Amazon MWAA console, navigate to the airflow-environment environment.
  3. Choose Open Airflow UI, and in the Airflow UI, choose the Admin dropdown menu and choose Plugins.
    You will see the BPGOperator plugin listed in the Airflow UI.
    Image showing BPGOperator plugin listed in the Airflow UI

Configure Airflow connections for BPG integration

This section guides you through setting up the Airflow connections that enable secure communication between your Amazon MWAA environment and BPG. BPGOperator uses the configured connection to authenticate and interact with BPG endpoints.

Execute the following script to configure the Airflow connection bpg_connection.

cd $REPO_DIR/airflow
./configure_connections.sh

In the Airflow UI, choose the Admin dropdown menu and choose Connections. You will see the bpg_connection listed in the Airflow UI.

Image showing Airflow Connections page with bpg_connection configured.

Configure the Airflow DAG to execute Spark jobs

This step configures an Airflow DAG to run a sample application. In this case, we will submit a DAG containing multiple sample Spark jobs using Amazon MWAA to EMR on EKS clusters using BPG. Please wait for few minutes for the DAG to appear in the Airflow UI.

cd $REPO_DIR/jobs
./configure_job.sh

Trigger the Amazon MWAA DAG

In this step, we trigger the Airflow DAG and observe the job execution behavior, including reviewing the Spark logs in the Airflow UI:

  1. In the Airflow UI, review the MWAASparkPipelineDemoJob DAG and choose the play icon trigger the DAG.
    Image showing sample Airflow Job, highlighting the play button to trigger the job
  2. Wait for DAG to complete successfully.
    Upon successful completion of the DAG, you should see Success:1 under the Runs column.
  3. In the Airflow UI, locate and choose the MWAASparkPipelineDemoJob DAG.
  4. On the Graph tab, choose any task (in this example, we select the calculate_pi task) and then choose the Logs
    Image showing the MWAASparkPipelineDemoJob's graph view
  5. View the Spark logs in the Airflow UI.
    Image showing the MWAASparkPipelineDemoJob calculate_pi task logs

Migrate existing Airflow DAGs to use BPG

In enterprise data platforms, a typical data pipeline consists of Amazon MWAA submitting Spark jobs to multiple EMR on EKS clusters using the SparkKubernetesOperator and an Airflow Connection of type Kubernetes. An Airflow Connection is a set of parameters and credentials used to establish communication between Amazon MWAA and external systems or services. A DAG refers to the connection name and connects to the external system.

The following diagram shows the typical architecture.
Image showing the existing job execution workflows not using BPG

In this setup, Airflow DAGs typically uses SparkKubernetesOperator and SparkKubernetesSensor to submit Spark jobs to a remote EMR on EKS cluster using kubernetes_conn_id=<connection_name>.

The following code snippet shows the relevant details:

# Submit Spark-Pi job using Kubernetes connection
submit_spark_pi = SparkKubernetesOperator(
	task_id='submit_spark_pi',
	namespace='default',
	application_file=spark_pi_yaml,
	kubernetes_conn_id='emr_on_eks_connection_[1|2]',  # Connection ID defined in Airflow
	dag=dag
)

To migrate the infrastructure to a BPG-based infrastructure without impacting the continuity of the environment, we can deploy a parallel infrastructure using BPG, create a new Airflow Connection for BPG, and incrementally migrate the DAGs to use the new connection. By doing so, we won’t disrupt the existing infrastructure until the BPG-based infrastructure is completely operational, including the migration of all existing DAGs.

The following diagram showcases the interim state where both the Kubernetes connection and BPG connection are operational. Blue arrows indicate the existing workflow paths, and red arrows represent the new BPG-based migration paths.

Image showing the existing workflow paths and the new bpg based migration path

The modified code snippet for the DAG is as follows:

# Submit Spark-Pi job using BPG connection
submit_spark_pi = BPGOperator(
	task_id='submit_spark_pi',
	application_file=spark_pi_yaml,
	application_file_type='yaml'
	connection_id='bpg_connection',  # Connection ID defined in Airflow
	dag=dag
)

Finally, when all the DAGs have been modified to use BPGOperator instead of SparkKubernetesOperator, you can decommission any remnants of the old workflow. The final state of the infrastructure will look like the following diagram.

Image showing the final state of the infrastructure after all the job migrations are complete.

Using this approach, we can seamlessly introduce BPG into an environment that currently uses only Amazon MWAA and EMR on EKS clusters.

Clean up

To avoid incurring future charges from the resources created in this tutorial, clean up your environment after you’ve completed the steps. You can do this by running the cleanup.sh script, which will safely remove all the resources provisioned during the setup:

cd ${REPO_DIR}/setup
./cleanup.sh

Conclusion

In the post Use Batch Processing Gateway to automate job management in multi-cluster Amazon EMR on EKS environments, we introduced Batch Processing Gateway as a solution for routing Spark workloads across multiple EMR on EKS clusters. In this post, we demonstrated how to enhance this foundation by integrating BPG with Amazon MWAA. Through our custom BPGOperator, we’ve shown how to build robust end-to-end Spark-based data processing pipelines while maintaining clear separation of responsibilities and centralized code management. Finally, we demonstrated how to seamlessly incorporate the solution into your existing Amazon MWAA and EMR on EKS data platform without impacting operational continuity.

We encourage you to experiment with this architecture in your own environment, adapting it to fit your unique workloads and operational requirements. By implementing this solution, you can build efficient and scalable data processing pipelines that use the full potential of EMR on EKS and Amazon MWAA. Explore further by deploying the solution in your AWS account while adhering to your organizational security best practices and share your experiences with the AWS Big Data community.


About the Authors

Suvojit DasguptaSuvojit Dasgupta is a Principal Data Architect at AWS. He leads a team of skilled engineers in designing and building scalable data solutions for AWS customers. He specializes in developing and implementing innovative data architectures to address complex business challenges.

Avinash DesireddyAvinash Desireddy is a Cloud Infrastructure Architect at AWS, passionate about building secure applications and data platforms. He has extensive experience in Kubernetes, DevOps, and enterprise architecture, helping customers containerize applications, streamline deployments, and optimize cloud-native environments.

Integrating aggregators and Quick Service Restaurants with AWS serverless architectures

Post Syndicated from Mike Gomez original https://aws.amazon.com/blogs/compute/integrating-aggregators-and-quick-service-restaurants-with-aws-serverless-architectures/

In this post, you learn how to use AWS serverless technologies, such as Amazon EventBridge and AWS Lambda, to build an integration between Quick Service Restaurants (QSRs) and online ordering and food delivery aggregators. These aggregators have taken off as an option to QSRs to expand their consumer base, enabling them with delivery options to help grow their businesses.

QSR overview

QSRs prioritize speedy and convenient service, offering a streamlined menu. To meet evolving consumer expectations, QSRs can use API integrations with third-party aggregators. This technological synergy enables QSRs to expand their capabilities, introducing diverse payment methods and incorporating delivery services. These features have become standard in this restaurant segment.

Behind the scenes, the APIs are used to orchestrate the interaction between the aggregator and the QSR while having a consistent ordering and delivery experience.

QSR business objectives are:

  • Providing consistent ordering and delivery experiences
  • Offering personalized menu items
  • Retaining repeat customers
  • Reducing third-party delivery cancellation due to lack of delivery personalization options

This post starts with a simple architecture and adds components to solve architectural challenges.

Architecture

As a solutions architect, you’ve been approached by a thriving local restaurant business seeking technological solutions to fuel their expansion. Your task is to design an optimal integration architecture that aligns with their technical requirements, streamlines operations, and enhances customer experience.

At the core of this integration is Amazon API Gateway, which accepts the incoming orders from various delivery aggregators. The API Gateway becomes the front door, connecting the QSRs with the end customers for a streamlined and dynamic order processing system.

Driving the backend of this integration are Lambda functions. These functions validate orders and securely communicate with delivery aggregators. Lambda functions can scale dynamically based on-demand, and make sure of optimal resource usage and cost-effectiveness.

Order placement workflow

The following steps outline the serverless integration between API Gateway and Lambda functions, as shown in the following figure:

  • Customers can place orders either through food delivery aggregators or the business’s own ordering system.
  • The order request is sent to API Gateway.

This architecture works for small and simple integrations. To scale this architecture for high traffic, use asynchronous integration to reduce the coupling between API and Lambda function.

Order routing workflow

The following steps outline a serverless integration where API Gateway connects to Lambda functions through Amazon EventBridge as the event routing service, as shown in the following figure:

  1. API Gateway receives the order request.
  2. The API Gateway routes the customer’s order request to an EventBridge bus for processing.

EventBridge routes events (for example order status changes) to Lambda functions, making sure of resiliency during service disruptions. This eliminates manual error handling and keeps QSRs and aggregators synchronized.

EventBridge delivers the following essential capabilities:

  • EventBridge receives events triggered by various actions, such as new orders or menu updates.
  • It routes events to the relevant Lambda functions, initiating the appropriate actions.
  • EventBridge supports event replay, allowing recovery from Lambda deployment issues or function failures. This feature enables business continuity by storing events during service disruptions and automatically resuming processing when the system stabilizes.

To maintain order history and enable fast data retrieval, the system needs a highly performant database. Amazon DynamoDB, a serverless NoSQL database service, meets these requirements by efficiently storing and managing order information and metadata. The order processing Lambda function interacts with DynamoDB to persist order details. This approach enables asynchronous processing of the stored data by other backend processes. The database solution provides the scalability and responsiveness needed to handle growing order volumes while maintaining consistent performance, separating order intake from subsequent processing steps.

Order processing workflow

The following steps outline the order processing workflow, as shown in the following figure:

  • The order processing Lambda function validates the order and updates the DynamoDB database with the new order details.
  • The function publishes error events to EventBridge, enabling downstream processing for error handling and retry logic. These events can trigger more Lambda functions designed to manage specific error scenarios and recovery processes.

EventBridge implementation patterns: single or dual bus approaches

EventBridge offers multiple approaches for event bus topology. Architects can choose to either use a single event bus with distinct event patterns based on order status or implement a multi-bus strategy.

The single-bus approach uses one event bus for all events with routing rule patterns based on order status. For example, rules would match specific statuses (for example “new” or “processed”) to trigger appropriate Lambda functions. Although it is architecturally simple, it needs careful management of the event schema to avoid potential errors. However, a single-bus approach requires careful handling to prevent recursive processing, where messages trigger additional messages in an endless loop.

Alternatively, the multi-bus method, separating order placement and processing across different buses, effectively prevents loops and recursion issues. This approach provides better separation of transactions, albeit with a slightly more complex setup.

EventBridge can directly target external services using the API destination option, eliminating the need for Lambda functions for third party integrations.

Orchestrating order processing

In complex order processing systems for QSRs, managing multiple interdependent Lambda functions can become challenging, potentially leading to intricate code and difficult-to-maintain architectures. To address this, AWS Step Functions can be introduced as an orchestration layer.

Step Functions acts as a central coordinator for the business logic needed in QSR order flows. This service manages the progression of activities in the order processing workflow, thereby efficiently coordinating tasks such as kitchen preparation and delivery logistics. Defining and managing complex workflows allows Step Functions to optimize the overall efficiency of QSR operations, providing a structured and adaptable solution. This orchestration enhances the restaurant’s ability to handle dynamic processing, achieving a smooth and responsive integration with delivery services while streamlining the underlying architecture.

The following steps outline the orchestration of order processing, as shown in the following figure:

  • Order processing trigger respective Lambda function, which updates the order data in the DynamoDB database.
  • The updated order is made available for subsequent Lambda functions that process more business logic being performed by further Lambda functions.

In a multi-bus EventBridge architecture, the process flows are as follows:

  1. The first EventBridge bus receives the initial order event and routes it to a Step Functions workflow.
  2. The Step Functions workflow orchestrates the order processing, coordinating various tasks and checks.
  3. Upon completion, the Step Functions workflow emits an event with the processing results to the second EventBridge bus.
  4. Based on the output from the Step Function workflow, this second bus contains a rule that triggers the Aggregator API as an API destination.

User engagement workflow

When a customer places an order, there must be a way to confirm or notify them when the order is ready. For this purpose, you can use AWS End User Messaging services to push notifications for order completion and new offers to customers.

Analyzing customer data and individual preferences allows Amazon Personalize to be used to present personalized recommendations and promotions.

Amazon Personalize can analyze historical order data to enhance the user experience through personalized recommendations, such as optimal delivery times, preferred menu items, and tailored promotions based on individual ordering patterns.

Conclusion

This post showed how to use AWS serverless services to build a platform for your order processing without worrying about managing underlying infrastructure. The serverless services included were Amazon API Gateway, AWS Lambda, Amazon EventBridge, AWS Step Functions, AWS End User Messaging, and Amazon Personalize.

This post is a brief introduction to event-driven architectures focused on integrations of internal ordering systems with delivery aggregators and third-party ordering platforms. This can help expand the user base, and it has been a key factor in the growth of many QSRs. Making the ordering, take-out, and delivery experience more efficient translates to revenue growth, reduction of order abandonment, as well as increased recurrent customer retention and brand loyalty.

For more serverless learning resources, visit Serverless Land. To find more patterns, go directly to the Serverless Patterns Collection.

AWS Lambda standardizes billing for INIT Phase

Post Syndicated from Shubham Gupta original https://aws.amazon.com/blogs/compute/aws-lambda-standardizes-billing-for-init-phase/

Effective August 1, 2025, AWS will standardize billing for the initialization (INIT) phase across all AWS Lambda function configurations. This change specifically affects on-demand invocations of Lambda functions packaged as ZIP files that use managed runtimes, for which the INIT phase duration was previously unbilled. This update standardizes billing of the INIT phase across all runtime types, deployment packages, and invocation modes. Most users will see minimal impact on their overall Lambda bill from this change, as the INIT phase typically occurs for a very small fraction of function invocations. In this post, we discuss the Lambda Function Lifecycle and upcoming changes to INIT phase billing. You will learn what happens in the INIT phase and when it occurs, how to monitor your INIT phase duration, and strategies to optimize this phase and minimize costs.

Understanding the Lambda function execution lifecycle

The Lambda function execution lifecycle consists of three distinct phases: INIT, INVOKE, and SHUTDOWN. The INIT phase is triggered during a “cold start” when Lambda creates a new execution environment for a function in response to an invocation. This is followed by the INVOKE phase where the request is processed, and finally, the SHUTDOWN phase where the execution environment is terminated. For a summary of the execution lifecycle, watch AWS Lambda execution environment lifecycle.

During the INIT phase, Lambda performs a series of preparatory steps within a maximum duration of 10 seconds. The service retrieves the function code from an internal Amazon S3 bucket, or from Amazon Elastic Container Registry (Amazon ECR) for functions using container packaging. Then, it configures an environment with the specified memory, runtime, and other settings. When the execution environment is prepared, Lambda executes four key tasks in sequence:

  1. Initiate any extensions configured (Extension INIT)
  2. Bootstrap the runtime (Runtime INIT)
  3. Execute the function’s static code (Function INIT)
  4. Run any before-checkpoint runtime hooks (applicable only for Lambda SnapStart)

Understanding the billing changes

Lambda charges are based on the number of requests and the duration it takes for the code to run. The duration is calculated from the moment the function code begins running until it completes or terminates, rounded up to the nearest millisecond. Duration cost depends on the amount of memory that you allocate to your function.
https://docs.aws.amazon.com/lambda/latest/dg/provisioned-concurrency.html
Previously, the INIT phase duration wasn’t included in the Billed Duration for functions using managed runtimes with ZIP archive packaging, as evidenced in Amazon CloudWatch logs:

REPORT RequestId: xxxxx   Duration: 250.06 ms  Billed Duration: 251 ms  Memory Size: 1024 MB
Max Memory Used: 350 MB   Init Duration: 100.77 ms

However, functions configured with custom runtimes, Provisioned Concurrency (PC), or OCI packaging already included the INIT phase duration in their Billed Duration. Effective August 1, 2025, INIT phase will be billed across all configuration types and the INIT phase duration will be included in the Billed Duration for on-demand invocations of functions using managed runtimes with ZIP archive packaging as well. After this change, the REPORT Request ID log line will show the following:

REPORT RequestId: xxxxx   Duration: 250.06 ms  Billed Duration: 351 ms  Memory Size: 1024 MB
Max Memory Used: 350 MB   Init Duration: 100.77 ms 

The further INIT phase duration charges will follow the standard on-demand duration pricing that is specific to each AWS Region, which can be found on the Lambda pricing page. For AWS Lambda@Edge functions, the INIT phase duration will be billed according to Lambda@Edge duration rates.

Finding the INIT phase duration and impact to Lambda billing

You can already monitor the time spent in the INIT phase of your function invocations using the “init_duration” CloudWatch metric. This metric is also reported as “Init Duration” in the “REPORT RequestId” log line within CloudWatch Logs. These tools offer valuable insights into the INIT time of Lambda functions, which will now be factored into billing calculations.

For a more comprehensive analysis, you can use the following CloudWatch Log Insights query to generate a detailed report estimating the previously unbilled duration of the INIT phase. The query helps you understand the proportion of the unbilled INIT phase time relative to your overall Lambda usage, enabling more accurate cost projections following this billing change.

filter @type = "REPORT" and @billedDuration < (@duration + @initDuration) 
| stats sum((@memorySize/1000000/1024) * (@billedDuration/1000)) as BilledGBs, 
sum((@memorySize/1000000/1024) * ((ceil(@duration + @initDuration) - @billedDuration)/1000)) as UnbilledInitGBs, 
(UnbilledInitGBs/ (UnbilledInitGBs+BilledGBs)) as Ratio

The CloudWatch Log Insights query provides three essential metrics:

  1. BilledGBs: Represents the total GB-s (gigabyte-seconds) currently being billed for the chosen log groups.
  2. UnbilledInitGBs: Shows the total GB-s consumed during INIT phase that was previously not included in billing.
  3. Ratio: Indicates the percentage of total GB-s attributed to previously unbilled INIT phase duration.

Using these existing monitoring capabilities allows you to proactively assess and optimize your Lambda function INIT times, potentially minimizing the impact of the new billing structure on your overall costs.

Understanding and optimizing Lambda INIT phase

The Lambda INIT phase is triggered in two specific scenarios: during the creation of a new execution environment and when a function scales up to meet demand. This INIT code runs only during these “cold starts” and is bypassed during subsequent invocations that use existing warm environments. After the INIT phase, Lambda runs the function handler code to process the invocation.

Following the handler execution, Lambda freezes the execution environment. To improve resource management and performance, the Lambda service retains the execution environment for a non-deterministic period of time. During this time, if another request arrives for the same function, then the service may reuse the environment. This second request typically finishes faster, because the execution environment already exists and it isn’t necessary to download the code and run the INIT code. This is called a “warm start.”

Developers can use the INIT phase to create, initialize, and configure objects expected to be reused across multiple invocations during function INIT instead of doing it in the handler. Initializing the dependencies/shared objects upfront reduces the latency of subsequent invocations. For example:

  • Download more libraries or dependencies
  • Establish client connections to other AWS services such as Amazon S3 or Amazon DynamoDB
  • Create database connections to be shared across invocations
  • Retrieve application parameters or secrets from Amazon Systems Manager Parameter Store or AWS Secrets Manager

When developing Lambda functions, it’s important to strategically decide what code runs during the INIT phase as opposed to the handler phase, because it affects both performance and costs.

Optimizing package/library size

The INIT phase includes creating an execution environment, downloading the function code and initializing it. Three main factors influence its performance:

  1. The size of the function package, in terms of imported libraries and dependencies, and Lambda layers.
  2. The amount of code and INIT work.
  3. The performance of libraries and other services in setting up connections and other resources.

Larger function packages increase code download times. You can decrease INIT phase duration by reducing package size, resulting in faster cold starts and lower INIT costs. Furthermore, optimizing loading of libraries can also significantly impact package size. For example, in Node.js functions, you should use specific path imports (for example import DynamoDB from "aws-sdk/clients/dynamodb") rather than wildcard imports (for example import {* as AWS} from "aws-sdk") to speed up the INIT phase. Tools such as esbuild can further optimize performance by minifying and bundling packages. For details, read Optimizing node.js dependencies in AWS Lambda.

Optimizing INIT phase execution and cost efficiency

The frequency of INIT phase executions (or cold starts) directly impacts both performance and cost efficiency. According to an analysis of production Lambda workloads, INITs (cold starts) typically occur in under 1% of invocations—meaning code in the INIT phase may execute just once per hundred invocations.

You can use the INIT phase to perform one-time operations that benefit subsequent invocations. Common optimization patterns include pre-calculating lookup tables or transforming static datasets. For example, downloading static data from Amazon S3 or DynamoDB during INIT, making it available for all subsequent function invocations without repeated downloads.

Lambda SnapStart

Lambda SnapStart provides an effective solution for reducing cold start latency and INIT phase costs. When it’s enabled, SnapStart creates a snapshot during the first function INIT and reuses it for subsequent cold starts, eliminating the need for repeated INIT phase executions. This approach is particularly valuable for functions with longer INIT times due to loading module dependencies/frameworks, initializing the runtime, or executing one-time INIT code. SnapStart is supported for Java, .NET, and Python runtimes. You can implement SnapStart through the Lambda console or AWS Command Line Interface (AWS CLI), making sure that your code adheres to the AWS serialization guidelines for snapshot restoration compatibility. Using SnapStart allows you to significantly improve function startup times and optimize costs across multiple popular programming languages.

Provisioned Concurrency

Provisioned Concurrency is a Lambda feature that pre-initializes execution environments before any invocations occur. This proactive approach effectively eliminates the performance impact of the INIT phase on individual function calls, because the INIT is completed in advance.

Although all functions using the Provisioned Concurrency benefit from reduced startup times as compared to on-demand execution, the impact is particularly pronounced for certain runtime environments. For example, C# and Java functions—which typically experience slower INIT but faster execution times as compared to Node.js or Python—can achieve significant performance gains through this feature. Implementing Provisioned Concurrency allows you to effectively manage both consistent traffic patterns and expected usage spikes, thereby minimizing cold start latency across your serverless applications. This optimization strategy is particularly valuable for functions with complex INIT requirements or those serving latency-sensitive workloads. From a cost optimization perspective, Provisioned Concurrency is most suitable for workloads with sustained usage patterns above 60% usage, because this typically provides better cost efficiency compared to on-demand execution.

Conclusion

Effective August 1, 2025, AWS is standardizing the INIT phase billing for AWS Lambda. AWS provides multiple ways for you to optimize both the performance and costs of your Lambda functions. Whether you’re using SnapStart, implementing Provisioned Concurrency, or optimizing INIT code, we recommend working closely with AWS support teams to identify the most suitable optimization approach for your specific workload requirements.

For more support and guidance, consider participating in AWS Cost Optimization workshops or consulting the Lambda documentation.

Read and write Apache Iceberg tables using AWS Lake Formation hybrid access mode

Post Syndicated from Aarthi Srinivasan original https://aws.amazon.com/blogs/big-data/read-and-write-apache-iceberg-tables-using-aws-lake-formation-hybrid-access-mode/

Enterprises are adopting Apache Iceberg table format for its multitude of benefits. The change data capture (CDC), ACID compliance, and schema evolution features cater to representing big datasets that receive new records at a fast pace. In an earlier blog post, we discussed how to implement fine-grained access control in Amazon EMR Serverless using AWS Lake Formation for reads. Lake Formation helps you centrally manage and scale fine-grained data access permissions and share data with confidence within and outside your organization.

In this post, we demonstrate how to use Lake Formation for read access while continuing to use AWS Identity and Access Management (IAM) policy-based permissions for write workloads that update the schema and upsert (insert and update combined) data records into the Iceberg tables. The bimodal permissions are needed to support existing data pipelines that use only IAM and Amazon Simple Storage Service (Amazon) S3 bucket policy-based permissions and to support table operations that are not yet available in the analytics engines. The two-way permission is achieved by registering the Amazon S3 data location of the Iceberg table with Lake Formation in hybrid access mode. Lake Formation hybrid access mode allows you to onboard new users with Lake Formation permissions to access AWS Glue Data Catalog tables with minimal interruptions to existing IAM policy-based users. With this solution, organizations can use the Lake Formation permissions to scale the access of their existing Iceberg tables in Amazon S3 to new readers. You can extend the methodology to other open table formats, such as Linux Foundation Delta Lake tables and Apache Hudi tables.

Key use cases for Lake Formation hybrid access mode

Lake Formation hybrid access mode is useful in the following use cases:

  • Avoiding data replication – Hybrid access mode helps onboard new users with Lake Formation permissions on existing Data Catalog tables. For example, you can enable a subset of data access (coarse vs. fine-grained access) for various user personas, such as data scientists and data analysts, without making multiple copies of the data. This also helps maintain a single source of truth for production and business insights.
  • Minimal interruption to existing IAM policy-based user access – With hybrid access mode, you can add new Lake Formation managed users with minimal disruptions to your existing IAM and Data Catalog policy-based user access. Both access methods can coexist for the same catalog table, but each user can have only one mode of permissions.
  • Transactional table writes – Certain write operations like insert, update, and delete are not supported by Amazon EMR for Lake Formation managed Iceberg tables. Refer to Considerations and limitations for additional details. Although you could use Lake Formation permissions for Iceberg table read operations, you could manage the write operations as the table owners with IAM policy-based access.

Solution overview

An example Enterprise Corp has a large number of Iceberg tables based on Amazon S3. They are currently managing the Iceberg tables manually with IAM policy, Data Catalog resource policy, and S3 bucket policy-based access in their organization. They want to share their transactional data of Iceberg tables across different teams, such as data analysts and data scientists, asking for read access across a few lines of business. While maintaining the ownership of the table’s updates to their single team, they want to provide restricted read access to certain columns of their tables. This is achieved by using the hybrid access mode feature of Lake Formation.

In this post, we illustrate the scenario with a data engineer team and a new data analyst team. The data engineering team owns the extract, transform, and load (ETL) application that will process the raw data to create and maintain the Iceberg tables. The data analyst team will query the tables to gather business insights from those tables. The ETL application will use IAM role-based access to the Iceberg table, and the data analyst gets Lake Formation permissions to query the same tables.

The solution can be visually represented in the following diagram.

Solution Overview

For ease of illustration, we use only one AWS account in this post. Enterprise use cases typically have multiple accounts or cross-account access requirements. The setup of the Iceberg tables, Lake Formation permissions, and IAM based permissions are similar for multiple and cross-account scenarios.

The high-level steps involved in the permissions setup are as follows:

  1. Make sure that IAMAllowedPrincipals has Super access to the database and tables in Lake Formation. IAMAllowedPrincipals is a virtual group that represents any IAM principal permissions. Super access to this virtual group is required to make sure that IAM policy-based permissions to any IAM principal continues to work.
  2. Register the data location with Lake Formation in hybrid access mode.
  3. Grant DATA LOCATION permission to the IAM role that manages the table with IAM policy-based permissions. Without the DATA LOCATION permission, write workloads will fail. Test the access to the table by writing new records to the table as the IAM role.
  4. Add SELECT table permissions to the Data-Analyst role in Lake Formation.
  5. Opt-in the Data-Analyst to the Iceberg table, making the Lake Formation permissions effective for the analyst.
  6. Test access to the table as the Data-Analyst by running SELECT queries in Athena.
  7. Test the table write operations by adding new records to the table as ETL-application-role using EMR Serverless.
  8. Read the latest update, again, as Data-Analyst.

Prerequisites

You should have the following prerequisites:

  • An AWS account with a Lake Formation administrator configured. Refer to Data lake administrator permissions and Set up AWS Lake Formation. You can also refer to Simplify data access for your enterprise using Amazon SageMaker Lakehouse for the Lake Formation admin setup in your AWS account. For ease of demonstration, we have used an IAM admin role added as a Lake Formation administrator.
  • An S3 bucket to host the sample Iceberg table data and metadata.
  • An IAM role to register your Iceberg table Amazon S3 location with Lake Formation. Follow the policy and trust policy details for a user-defined role creation from Requirements for roles used to register locations.
  • An IAM role named ETL-application-role, which will be the runtime role to execute jobs in EMR Serverless. The minimum policy required is shown in the following code snippet. Replace the Amazon S3 data location of the Iceberg table, database name, and AWS Key Management Service (AWS KMS) key ID with your own. For additional details on the role setup, refer to Job runtime roles for Amazon EMR Serverless. This role can insert, update, and delete data in the table.
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Sid": "IcebergDataAccessInS3",
                "Effect": "Allow",
                "Action": [
                    "s3:ListBucket",
                    "s3:GetBucketLocation",
                    "s3:ListAllMyBuckets",
                    "s3:Get*",
                    "s3:Put*",
                    "s3:Delete*"
                ],
                "Resource": [
                    "arn:aws:s3:::your-iceberg-data-bucket-name",
                    "arn:aws:s3:::your-iceberg-data-bucket-name/*"
                ]
            },
            {
                "Sid": "GlueCatalogApiPermissions",
                "Effect": "Allow",
                "Action": [
                    "glue:*"
                ],
                "Resource": [
                    "arn:aws:glue:your-Region:account-id:catalog",
                    "arn:aws:glue:your-Region:account-id:database/iceberg-database-name",
                    "arn:aws:glue:your-Region:account-id:database/default",
                    "arn:aws:glue:your-Region:account-id:table/*/*"
                ]
            },
            {
                "Sid": "KmsKeyPermissions",
                "Effect": "Allow",
                "Action": [
                    "kms:Encrypt",
                    "kms:Decrypt",
                    "kms:ReEncrypt*",
                    "kms:GenerateDataKey",
                    "kms:DescribeKey",
                    "kms:ListKeys",
                    "kms:ListAliases"
                ],
                "Resource": [
                    "arn:aws:kms:your-Region:account-id:key/your-key-id"
                ]
            }
        ]
    }

    Add the following trust policy to the role:

    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Effect": "Allow",
                "Principal": {
                    "Service": "emr-serverless.amazonaws.com"
                },
                "Action": "sts:AssumeRole"
            }
        ]
    }

  • An IAM role called Data-Analyst, to represent the data analyst access. Use the following policy to create the role. Also attach the AWS managed policy arn:aws:iam::aws:policy/AmazonAthenaFullAccess to the role, to allow querying the Iceberg table using Amazon Athena. Refer to Data engineer permissions for additional details about this role.
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Sid": "LFBasicUser",
                "Effect": "Allow",
                "Action": [
                    "glue:GetCatalog",
                    "glue:GetCatalogs",
                    "glue:GetTable",
                    "glue:GetTables",
                    "glue:GetTableVersion",
                    "glue:GetTableVersions",
                    "glue:GetDatabase",
                    "glue:GetDatabases",
                    "glue:GetPartition",
                    "glue:GetPartitions",
                    "lakeformation:GetDataAccess"
                ],
                "Resource": "*"
            },
            {
                "Sid": "AthenaResultsBucket",
                "Effect": "Allow",
                "Action": [
                    "s3:ListBucket",
                    "s3:GetBucketLocation",
                    "s3:Put*",
                    "s3:Get*",
                    "s3:Delete*"
                ],
                "Resource": [
                    "arn:aws:s3:::your-bucket-name-prefix",
                    "arn:aws:s3:::your-bucket-name-prefix/*"
                ]
            }
        ]
    }

    Add the following trust policy to the role:

    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Effect": "Allow",
                "Principal": {
                    "AWS": "arn:aws:iam::<your_account_id>:root"
                },
                "Action": "sts:AssumeRole"
            }
        ]
    }

Create the Iceberg table

Complete the following steps to create the Iceberg table:

  1. Sign in to the Lake Formation console as the admin role.
  2. In the navigation pane under Data Catalog, choose Databases.
  3. From the Create dropdown menu, create a database named iceberg_db. You can leave the Amazon S3 location property empty for the database.
  4. On the Athena console, run the following provided queries. The queries perform the following operations:
    1. Create a table called customer_csv, pointing to the customer dataset in the public S3 bucket.
    2. Create an Iceberg table called customer_iceberg, pointing to your S3 bucket location that will host the Iceberg table data and metadata.
    3. Insert data from the CSV table to the Iceberg table.
      CREATE EXTERNAL TABLE `iceberg_db`.`customer_csv`(
        `c_customer_sk` int,
        `c_customer_id` string,
        `c_current_cdemo_sk` int,
        `c_current_hdemo_sk` int,
        `c_current_addr_sk` int,
        `c_first_shipto_date_sk` int,
        `c_first_sales_date_sk` int,
        `c_salutation` string,
        `c_first_name` string,
        `c_last_name` string,
        `c_preferred_cust_flag` string,
        `c_birth_day` int,
        `c_birth_month` int,
        `c_birth_year` int,
        `c_birth_country` string,
        `c_login` string,
        `c_email_address` string,
        `c_last_review_date` string)
      ROW FORMAT DELIMITED
        FIELDS TERMINATED BY '|'
      STORED AS INPUTFORMAT
        'org.apache.hadoop.mapred.TextInputFormat'
      OUTPUTFORMAT
        'org.apache.hadoop.hive.ql.io.HiveIgnoreKeyTextOutputFormat'
      LOCATION
        ' s3://redshift-downloads/TPC-DS/2.13/10GB/customer/'
      TBLPROPERTIES (
        'classification'='csv');   
      
       SELECT * FROM customer_csv LIMIT 5; //verifies table data  
      
      CREATE TABLE IF NOT EXISTS iceberg_db.customer_iceberg (
              c_customer_sk             int,
              c_customer_id             string,
              c_current_cdemo_sk        int,
              c_current_hdemo_sk        int,
              c_current_addr_sk         int,
              c_first_shipto_date_sk    int,
              c_first_sales_date_sk     int,
              c_salutation              string,
              c_first_name              string,
              c_last_name               string,
              c_preferred_cust_flag     string,
              c_birth_day               int,
              c_birth_month             int,
              c_birth_year              int,
              c_birth_country           string,
              c_login                   string,
              c_email_address           string,
              c_last_review_date        string
          )
      LOCATION 's3://your-iceberg-data-bucket-name/path/'
      TBLPROPERTIES ( 'table_type' = 'ICEBERG' );
      
      INSERT INTO customer_iceberg
      SELECT *
      FROM customer_csv;  
      
      SELECT * FROM customer_iceberg LIMIT 5; //verifies table data

Set up the Iceberg table as a hybrid access mode resource

Complete the following steps to set up the Iceberg table’s Amazon S3 data location as hybrid access mode in Lake Formation:

  1. Register your table location with Lake Formation:
    1. Sign in to the Lake Formation console as data lake administrator.
    2. In the navigation pane, choose Data lake Locations.
    3. For Amazon S3 path, provide the S3 prefix of your Iceberg table location that holds both the data and metadata of the table.
    4. For IAM role, provide the user-defined role that has permissions to your Iceberg table’s Amazon S3 location and that you created according to the prerequisites. For more details, refer to Registering an Amazon S3 location.
    5. For Permission mode, select Hybrid access mode.
    6. Choose Register location to register your Iceberg table Amazon S3 location with Lake Formation.

  1. Add data location permission to ETL-application-role:
    1. In the navigation pane, choose Data locations.
    2. For IAM users and roles, choose ETL-application-role.
    3. For Storage location, provide the S3 prefix of your Iceberg table.
    4. Choose Grant.

Data location permission is required for write operations to the Iceberg table location only if the Iceberg table’s S3 prefix is a child location of the database’s Amazon S3 location property.

  1. Grant Super access on the Iceberg database and table to IAMAllowedPrincipals:
    1. In the navigation pane, choose Data permissions.
    2. Choose IAM users and roles and choose IAMAllowedPrincipals.
    3. For LF-Tags or catalog resources, choose Named Data Catalog resources.
    4. Under Databases, select the name of your Iceberg table’s database.
    5. Under Database permissions, select Super.
    6. Choose Grant.

    7. Repeat the preceding steps and for Tables – optional, choose the Iceberg table.
    8. Under Table permissions, select Super.
    9. Choose Grant.

  1. Add database and table permissions to the Data-Analyst role:
    1. Repeat the steps in Step 3 to grant permissions for the Data-Analyst role, once for database-level permission and once for table-level permission.
    2. Select Describe permissions for the Iceberg database.
    3. Select Select permissions for the Iceberg table.
    4. Under Hybrid access mode, select Make Lake Formation permissions effective immediately.
    5. Choose Grant.

The following screenshots show the database permissions for Data-Analyst.

The following screenshots show the table permissions for Data-Analyst.

  1. Verify Lake Formation permissions on the Iceberg table and database to both Data-Analyst and IAMAllowedPrincipals:
    1. In the navigation pane, choose Data permissions.
    2. Filter by Table= customer_iceberg.
      You should see IAMAllowedPrincipals with All permission and Data-Analyst with Select permission.
    3. Similarly, verify permissions for the database by filtering database=iceberg_db.

You should see IAMAllowedPrincipals with All permission and Data-Analyst with Describe permission.

  1. Verify Lake Formation opt-in for Data-Analyst:
    1. In the navigation pane, choose Hybrid access mode.

You should see Data-Analyst opted-in for both database and table level permissions.

Query the table as the Data-Analyst role in Athena

While you are logged in to the AWS Management Console as admin, set up the Athena query results bucket:

  1. On the console navigation bar, choose your user name.
  2. Choose Switch role to switch to the Data-Analyst role.
  3. Enter your account ID, IAM role name (Data-Analyst), and choose Switch Role.
  4. Now that you’re logged in as the Data-Analyst role, open the Athena console and set up the Athena query results bucket.
  5. Run the following query to read the Iceberg table. This verifies the Select permission granted to the Data-Analyst role in Lake Formation.
SELECT * FROM "iceberg_db"."customer_iceberg"
WHERE c_customer_sk = 247

Upsert data as ETL-application-role using Amazon EMR

To upsert data to Lake Formation enabled Iceberg tables, we will use Amazon EMR Studio, which is an integrated development environment (IDE) that makes it straightforward for data scientists and data engineers to develop, visualize, and debug data engineering and data science applications written in R, Python, Scala, and PySpark. EMR Studio will be our web-based IDE to run our notebooks, and we will use EMR Serverless as the compute engine. EMR Serverless is a deployment option for Amazon EMR that provides a serverless runtime environment. For the steps to run an interactive notebook, see Submit a job run or interactive workload.

  1. Sign out of the AWS console as Data-Analyst and log back or switch the user to admin.
  2. On the Amazon EMR console, choose EMR Serverless in the navigation pane.
  3. Choose Get started.
  4. For first-time users, Amazon EMR allows creation of an EMR Studio without a virtual private cloud (VPC). Create an EMR Serverless application as follows:
    1. Provide a name for the EMR Serverless application, such as DemoHybridAccess.
    2. Under Application setup, choose Use default settings for interactive workloads.
    3. Choose Create and start application.

The next step is to create an EMR Studio.

  1. On the Amazon EMR console, choose Studio under EMR Studio in the navigation pane.
  2. Choose Create Studio.
  3. Select Interactive workloads.
  4. You should see a default pre-populated section. Keep these default settings and choose Create Studio and launch Workspace.

  1. After the workspace is launched, attach the EMR Serverless application created earlier and select ETL-application-role as the runtime role under Compute.

  1. Download the notebook Iceberg-hybridaccess_final.ipynb and upload it to EMR Studio workspace.

This notebook configures the metastore properties to work with Iceberg tables. (For more details, see Using Apache Iceberg with EMR Serverless.) Then it performs insert, update, and delete operations in the Iceberg table. It also verifies if the operations are successful by reading the newly added data.

  1. Select PySpark as the kernel and execute each cell in the notebook by choosing the run icon.

Refer to Submit a job run or interactive workload for further details about how to run an interactive notebook.

The following screenshot shows that the Iceberg table insert operation completed successfully.

The following screenshot illustrates running the update statement on the Iceberg table in the notebook.

The following screenshot shows that the Iceberg table delete operation completed successfully.

Query the table again as Data-Analyst using Athena

Complete the following steps:

  1. Switch your role to Data-Analyst on the AWS console.
  2. Run the following query on the Iceberg table and read the row that was updated by the EMR cluster:
    SELECT * FROM "iceberg_db"."customer_iceberg"
    WHERE c_customer_sk = 247

The following screenshot shows the results. As we can see, ‘c_first_name’ column is updated with new value.

Clean up

To avoid incurring costs, clean up the resources you used for this post:

  1. Revoke the Lake Formation permissions and hybrid access mode opt-in granted to the Data-Analyst role and IAMAllowedPrincipals.
  2. Revoke the registration of the S3 bucket to Lake Formation.
  3. Delete the Athena query results from your S3 bucket.
  4. Delete the EMR Serverless resources.
  5. Delete Data-Analyst role and ETL-application-role from IAM.

Conclusion

In this post, we demonstrated how to scale the adoption and use of Iceberg tables using Lake Formation permissions for read workloads, while maintaining full control over table schema and data updates through IAM policy-based permissions for the table owners. The methodology also applies to other open table formats and standard Data Catalog tables, but the Apache Spark configuration for each open table format will vary.

Hybrid access mode in Lake Formation is an option you could use to adopt Lake Formation permissions gradually and scale those use cases that support Lake Formation permissions while using IAM based permissions for the use cases that don’t. We encourage you to try out this setup in your environment. Please share your feedback and any additional topics you would like to see in the comments section.


About the Authors

Aarthi Srinivasan is a Senior Big Data Architect with AWS Lake Formation. She collaborates with the service team to enhance product features, works with AWS customers and partners to architect lake house solutions, and establishes best practices.

Parul Saxena is a Senior Big Data Specialist Solutions Architect in AWS. She helps customers and partners build highly optimized, scalable, and secure solutions. She specializes in Amazon EMR, Amazon Athena, and AWS Lake Formation, providing architectural guidance for complex big data workloads and assisting organizations in modernizing their architectures and migrating analytics workloads to AWS.

Empower your teams with modern architecture governance

Post Syndicated from Rostislav Markov original https://aws.amazon.com/blogs/architecture/empower-your-teams-with-modern-architecture-governance/

Agile product teams thrive on autonomy and rapid iteration, especially in the cloud where they can quickly deploy and test systems. However, traditional architecture governance often stands in their way, because many enterprises still impose centralized, one-off architecture signoffs early in the process. Historically, these signoffs verified design compliance with corporate standards in a slower, on-premises world. In cloud environments, such signoffs quickly become obsolete—along with their associated architectural documents—and discourage teams from considering new insights.

Modern cloud architectures demand a new governance approach. In this post, we show how collaborative architecture oversight can transform team performance through automation, self-service platforms, and distributed decision-making. We explore how key stakeholders (developers, architects, security specialists, and shared services teams) can participate in architectural decisions through asynchronous approval workflows, while making sure non-negotiable controls such as encryption at rest and in transit are consistently enforced through automation and policy as code. This approach empowers teams to experiment and adapt quickly while maintaining robust enterprise standards.

The promise of traditional architecture signoffs

Traditional architecture governance centers around formal reviews where teams submit detailed design documents to a central architecture board. These artifacts often include comprehensive diagrams, technology selections, security plans, and integration specifications. Architects and a variety of stakeholders such as security specialists, compliance officers, quality assurance, and operations teams review these documents in scheduled meetings before issuing a signoff. These approvals represent point-in-time validations against enterprise standards, assuming minimal deviation during implementation.

Why traditional signoffs fall short

Signoffs can create challenges in modern cloud architectures:

  • Substituting for continuous compliance when automated verification is missing, creating false assurance through one-off reviews
  • Creating a restrictive “check-the-box” mentality where meeting minimum documented requirements becomes the goal instead of exploring the best solutions
  • Removing decision authority from implementation teams who often have the most contextual knowledge
  • Delaying implementation feedback loops and reducing organizational agility

Consider an agile team responsible for a strategic cloud application that’s moved beyond minimal viable product and is now scaling to support growing business demands. The system architecture must evolve to handle increasing data volumes, performance requirements, and unanticipated integrations. However, corporate stakeholders insist on rigid adherence to the originally approved architecture documents. Although governance is essential for production systems, this inflexible approach with an early architecture signoff prevents the team from implementing architectural improvements as they go. What appears as meaningful control to stakeholders becomes a stifling constraint for builders, ultimately compromising the system stability the governance process aims to protect.

Modern cloud architecture support

A modern architecture function operates around evolving capabilities across three core areas: preapproved blueprints, distributed governance, and automated insights—with traditional signoffs reserved as an exception path for unique use cases.

A modern architecture function operates around evolving capabilities across three core areas: preapproved blueprints, distributed governance, and automated insights—with traditional signoffs reserved as an exception path for unique use cases.

Preapproved blueprints

Preapproved blueprints like reference architectures and code templates enable your teams to move faster while maintaining corporate standards. This approach supports a use-case-focused assessment model, where architects can concentrate on evaluating specific workflows or threats relevant to a unique use case—rather than having to understand the entire system or threat model from scratch. In this way, the architecture function shifts to managing by exception and refocus reviews on deviations from the standard. Blueprints should have gravity, guiding teams towards standardized patterns while preventing fragmentation through too many tools, databases, middleware options, or SDKs. Consider the following:

  • Pattern-based reference architectures – These set clear principles for security and resilience without micromanaging. These standards align teams while allowing innovation within a reliable framework. The cloud-driven enterprise transformation at BMW Group exemplifies how moving from signoffs to enablement through pattern-based architectures can be successful.
  • Self-service platforms – These provide standardized resources that empower teams to build independently. A self-service platform with preapproved templates for deployment toolchains and infrastructure code enables confident and rapid development. Most companies host these on internal developer platforms like Backstage or AWS Service Catalog. This also allows controlled changes to the blueprints and to track their adoption.
  • Blueprint lifecycle – Blueprints require their own approval process. Although this creates significant efficiency by reducing individual system reviews, it introduces the challenge of managing existing deployments when patterns are updated. Include versioning and migration strategies when introducing new blueprints.

Distributed governance

Distributed governance treats architectural decision-making as a continuous, collaborative process with clear accountability, delegating decision-making and empowering your builders within established blueprints. Consider the following:

  • Architecture decision records (ADRs) – These replace formal, one-off signoffs by documenting decisions for each build iteration. This approach promotes transparency and maintains team agility without compromising accountability for decisions and approvals with key stakeholders. It also allows teams to defer decisions until they are most relevant. For practical implementation guidance, see Using architectural decision records to streamline decision-making for a software development project. To learn about how to write concise ADRs and avoid duplication, consult the ADR templates GitHub repository and When Should I Write an Architecture Decision Record.
  • Community-driven consultations – Architecture departments can foster self-organization by creating architecture communities of practice for peer knowledge-sharing. These communities enable collaboration on best practices, challenges, and standards, cultivating a culture of distributed decision-making, without eliminating the lines of responsibility and accountability for final decisions. This approach works because deep architectural expertise often resides with builders who have hands-on experience with specific use cases and technologies. The role of the architecture function shifts towards providing the necessary infrastructure and identifying thought leaders in the organization.

Automated insights

Automated insights enable compliance with corporate standards through real-time monitoring and adaptation:

Comparison

The modern view improves the overall value-add and support model of your architecture function. The following table compares the traditional and modern views.

Aspect Traditional View Modern View
Purpose Centralized signoff to enforce control and reduce risk Empower teams with preapproved standards to prevent sprawl and manage their distribution such as through Backstage
Architecture approach Fixed, one-time design Evolving, treated as a parametrized, reusable code product refined through feedback
Team empowerment Limited, decisions approved by centralized authority High, teams make decisions within clear standards
Team speed and agility Slower, due to dependency on signoff Faster, continuous iteration without waiting for approvals
Risk management Early signoff to lock in decisions and reduce uncertainty Risk managed through continuous control validation with automated evidence collection, providing stronger assurance for second and third lines of defense than point-in-time assessments
Compliance Manual checks by experts Automated through policy as code and AI tools
Transparency Limited, focused on approval documentation High, lightweight decision records for technical stakeholders and visualizations or dashboards for non-technical oversight functions
Collaboration Centralized control, limited cross-team collaboration Peer-led communities (collective governance) such as Security Guardians
Innovation Restricted, focus on following signed-off designs Encouraged, teams explore within a standards-based framework

Despite the benefits, many organizations struggle to let go of signoffs for a number of reasons, including:

  • Cultural resistance – In risk-averse cultures where failing fast is not accepted, leaders hesitate to let go of centralized control mechanisms.
  • Compliance concerns – In regulated industries, centralized approvals serve as control gates. The modern view replaces point-in-time trust with continuous compliance mechanisms—automated guardrails, real-time monitoring, and evidence collection—enabling even highly regulated environments to achieve compliance with small, autonomous teams operating within clear boundaries (“two-pizza team”).
  • Lack of infrastructure – Some organizations lack self-service platforms, automated compliance, or observability, so they fall back on signoff to manage risk.
  • Governance concerns – Traditional teams often view distributed decision-making as no governance rather than transformed governance.

The modern view offers significant benefits, though with governance considerations:

  • Speed and flexibility – Teams move faster without waiting for approvals, deploying AWS resources iteratively.
  • Empowerment and ownership – Builders using standards and ADRs feel accountable and actively shape architecture.
  • Innovation and experimentation – Self-service tools and AI guidance foster experimentation without delays.

Conclusion

You can empower your builders by rethinking your architecture signoff. In the modern view discussed in this post, architecture governance aligns with the pace and flexibility of the cloud, allowing teams to innovate within a shared framework. This approach values standards and autonomy over control, and transforms your architecture function into a strategic partner in a fast-evolving landscape.

To learn how to establish and maintain cloud-centered principles and patterns, refer to the platform architecture chapter of the AWS Cloud Adoption Framework and the AWS Culture of Security resources.

Related resources


About the author

Build and operate an effective architecture review board

Post Syndicated from Darrin Weber original https://aws.amazon.com/blogs/architecture/build-and-operate-an-effective-architecture-review-board/

The rapid change of pace in computing landscapes because of cloud, artificial intelligence, and technology innovation has challenged organizations to keep up while making sure that their initiatives and projects remain compliant with enterprise guidelines and policies. An effective architecture review board (ARB) can help an organization maintain compliance with enterprise guardrails while accelerating implementation of initiatives in their project pipeline.

In this post, we identify the components of an efficient architecture review process, define what an ARB is, and describe how to build and operate an effective enterprise ARB.

What is an architecture review board?

An ARB is a multi-disciplinary team responsible for reviewing solution architectures to help ensure compliance with enterprise guidelines, best practices, and supportability. Team members include stakeholders from different disciplines throughout your organization, which typically include Security, Development, Enterprise Architecture, Infrastructure, and Operations. Including a broad set of stakeholders reduces the amount of project recycle that happens when stakeholder representation is overlooked.

An ARB isn’t a standalone group, it operates within the context of your project implementation process, reviewing solution architectures, custom development, and purchased solutions to maintain enterprise compliance and alignment with goals. As shown in the following diagram, architecture review typically occurs after the design phase—before a build or purchase decision—and again before deployment to validate that the reviewed architecture matches the solution that was built.

Project implementation process with architecture review checkpoints

Most organizations recognize the benefits and value of establishing an ARB. However, they often struggle to define and operate one in a manner that maximizes the benefits, integrates with overall project execution processes, and satisfies the needs of all the stakeholders. An efficient architecture review process imparts organizational benefits such as reduced costs, minimized security events, and diminished technical debt.

Life without a formal architecture review process

One of the most pronounced issues with implementing and maintaining software architecture is the difficulty in achieving human consensus. In any organization, you’ll find a diverse range of team members—each with their own priorities, perspectives, and pain points. Without a formalized review process, these differences can lead to prolonged debates and stalled projects. We often find that many members tend to fall into one of these personas:

The Not Invented Here The Not Invented Here – This individual doesn’t trust any software unless it was built and operated by members of their company. They’re generally wary of any cloud solution and will expend development time to avoid capital expenditure.
The Wait a Minute The Wait a Minute – This individual has good feedback and their input is welcome, but they tend to wait until the last minute before providing any feedback, making it difficult to have productive conversations and act on any constructive criticism.
The Bottleneck The Bottleneck – This individual craves control and insists that all reviews, decisions, and conversations go through them. This makes scaling the architecture review process very challenging and decisions will often come down to the whim of this one person.
The Creative The Creative – This individual has passion for software and for creating things, but will often choose complexity over simplicity and turn their architectures into art projects.
The Perfectionist The Perfectionist – This individual tends to let the perfect be the enemy of the good. While their intentions are pure, this approach can result in delayed decision making and debates on topics that might not be worth the time of the board.
The Historian The Historian – This individual has been at the company for a long time and remembers every success and failure along the way. While the context this individual brings to the table is invaluable, teams must guard against only looking to the past as they try to shape the future.

Benefits of an architecture review board

Establishing an ARB within your organization can yield substantial benefits, enhancing both the quality and efficiency of your architecture. Some key advantages are:

Improved compliance

By systematically reviewing architectural decisions, the ARB helps ensure that designs adhere to company best practices, open standards, and regulatory requirements as set forth by your enterprise architecture.

Reduced technical debt

Technical debt—taking shortcuts in the development process that lead to future complications—is a common issue in software development. The ARB helps identify and mitigate technical debt early in the design phase. By enforcing architectural standards and promoting best practices, the board helps ensure that decisions are made with long-term sustainability in mind. This approach results in more robust, maintainable codebases and reduces the likelihood of future rework.

Efficiency with lowered costs

While a formal architecture review sounds like it might have the potential for increased red tape and lowered efficiency, the ARB instead contributes to operational efficiency by standardizing architectural practices across the organization. This uniformity allows for better resource allocation, faster deployment cycles, and more predictable project timelines. By catching potential issues early in the design phase, the ARB helps avoid costly rewrites and rework, which can lead to significant cost savings over time.

Supportability

Designing for supportability is crucial for the long-term success of any application. The ARB makes sure that architectures are built with maintainability in mind, making it easier for operations teams to manage and troubleshoot systems. This focus on supportability leads to fewer downtime incidents, faster resolution times, and overall higher system reliability. By making sure the composition of the ARB crosses all parts of the organization, supportability concerns can be surfaced earlier and help ensure that changes are properly socialized.

Security

Above all, security is the most critical output of an effective ARB. The ARB plays a pivotal role in embedding security into the architectural fabric from the outset. By conducting thorough security reviews and incorporating security best practices into every design, the ARB makes sure that applications are resilient against unintended disclosure, inadvertent access, and threat actors. This proactive approach not only protects sensitive data, but also builds trust with your customers and stakeholders.

Steps for effective architecture review boards

Whether looking to establish a new architecture review process or improve the effectiveness of a current ARB, we’ve identified eight key steps to make sure that an ARB operates in a way which realizes the benefits of a robust architecture review process while maintaining enterprise compliance. With the exception of leadership support, the steps aren’t presented in a particular order and can be implemented in parallel or in whatever order fits your organization and resource availability.

Leadership support

Identifying a sponsor on the executive leadership team is crucial to the success of the ARB. An executive sponsor fosters participation from stakeholders, representing key organizations such as Security, Development, and Operations, along with gaining their commitment to the review processes. The executive sponsor helps embed the ARB function within the enterprise’s project implementation process. Supported by the executive sponsor, the ARB’s reviews serve as a formal gate within the project process, reducing attempts to bypass the review processes.

Single source for guidance, policies, and best practices

Establish a single, well-known repository or index so that the entire enterprise has a single source of truth that establishes the basis for designing and reviewing architecture. A common repository doesn’t need to be complex. It can be a central document location, wiki, or file share that’s quickly discoverable. Commonly, an enterprise’s collection of guidelines and policies are dispersed and managed by each organization using different mechanisms and repositories. Best practices are often treated as folklore passed between team members. Project teams and ARB stakeholders need to share a common understanding of the enterprise’s collective intelligence consisting of guidelines, policies, and best practices.

As the project community’s collective understanding of the enterprise guidelines and policies grows, initial solution designs are better aligned, and reviews through the ARB accelerate. After a common repository is established, consider using generative AI to create a natural language chatbot, a design chatbot, to simplify access to the collective guidelines, policies, and best practices. See Amazon Bedrock or Amazon Q – Generative AI Assistant.

Defined stakeholders

Make sure that your disciplines have defined stakeholders on the ARB. A good starting point is to identify stakeholders from the Security, Enterprise Architecture, Development, Infrastructure, and Operations teams. Broad representation on the board minimizes recycles and delays later in the project, which can occur when stakeholders aren’t engaged in the review process from the beginning. A stakeholder’s responsibility is to focus on their area of subject matter expertise and commit a portion of their time to the ARB. Consider rotating stakeholders periodically to distribute knowledge and workload through the organization.

Gated process with documented decisions

As previously described, architecture reviews typically occur after design and before solution implementation or purchase. Optionally, another architecture review takes place before deployment to validate that the solution matches what was reviewed and approved. It’s important to complete the review before implementation or the purchase decision and to get stakeholder sign off. Otherwise, projects risk rework and delay later in the process, often impacting cost or schedule to a greater degree. Document each ARB action, including approvals, reasons for recycles, exceptions required, follow-ups needed, and so on. Documented decisions should be added to the project’s overall lifecycle documentation to benefit future inspection of project or similar solution architectures.

Establish an exception process

There will always be exceptions to your enterprise guidelines or policies. Plan for exceptions with a defined process for reviewing, escalating, and gaining approval. Include leadership from both IT and business areas in the assessment and sign-off on an exception. Most importantly, set expiration dates on the exceptions–they should not be granted indefinitely. Exceptions are typically granted to accommodate a temporary nonconformance to provide time to plan for and implement a better, long-term solution.

Architecture central repository

Establish a well known, central repository for solution architecture documents. Solution documentation should be treated as living artifacts that are maintained for the lifecycle of the use case. A central architecture repository benefits teams responsible for operating and maintaining solutions, along with design teams chartered with new solution design. After a repository is established, consider including your architecture documentation in the generative AI design chatbot mentioned previously.

Automate review process

Employ automated architecture review processes wherever possible. Automated review processes allow stakeholders to focus their time on their subject matter expertise instead of administrative tasks. Consider separate review processes based on an initiative’s complexity, cost, and impact. Schedule live meetings with the ARB for the most complex and impactful solutions, and use offline mechanisms, such as email, for other efforts. Define a universal architecture template to capture areas of interest for review and automate the Q&A and sign-off processes. Consider using generative AI to do initial automated design reviews against enterprise core best practices and policies to further streamline stakeholder review processes.

Architecture review process shepherd

Identify a shepherd to help ensure that solution architectures are reviewed and the ARB review processes are broadly understood. The shepherd functions as a liaison with executive sponsors for exceptions. While the shepherd can also be a stakeholder on the board, the shepherd is not the single overall decision maker. The shepherd champions the continuous improvement of the architecture review process and mechanisms.

Conclusion

In this post, we explored the benefits of establishing an architecture review board within an organization, emphasizing its role in maintaining compliance, reducing technical debt, and enhancing operational efficiency. We discussed the challenges organizations face in setting up an effective ARB and provided guidance on the essential components and steps required to build and operate a successful ARB. By following the outlined steps, organizations can maximize the benefits of an ARB, making sure that architectural decisions align with enterprise goals and standards while fostering a culture of continuous improvement and stakeholder collaboration.

For additional guidance on garnering the leadership support necessary for an effective ARB, see Well-Architected Framework: Provide executive sponsorship. For more details on the review process, see Well-Architected Framework: The review process and AWS Well-Architected Tool, an AWS Management Console-based service that provides a consistent process for measuring your architecture using AWS best practices. If you’re interested in establishing a natural language chatbot interface for your enterprise architecture information, see Amazon Bedrock, Amazon Q Business, or Build a contextual chatbot application using Amazon Bedrock Knowledge Bases.


About the authors

Integrate ThoughtSpot with Amazon Redshift using AWS IAM Identity Center

Post Syndicated from Maneesh Sharma original https://aws.amazon.com/blogs/big-data/integrate-thoughtspot-with-amazon-redshift-using-aws-iam-identity-center/

Amazon Redshift is a fast, scalable, and fully managed cloud data warehouse that allows you to process and run your complex SQL analytics workloads on structured and semi-structured data. Tens of thousands of customers use Amazon Redshift to process large amounts of data, modernize their data analytics workloads, and provide insights for their business users.

The combination of Amazon Redshift and ThoughtSpot’s AI-powered analytics service enables organizations to transform their raw data into actionable insights with unprecedented speed and efficiency. Through this collaboration, Amazon Redshift now supports AWS IAM Identity Center integration with ThoughtSpot, enabling seamless and secure data access with streamlined authentication and authorization workflows. This single sign-on (SSO) integration is available across ThoughtSpot’s cloud landscape and can be used for both embedded and standalone analytics implementations.

Prior to the IAM Identity Center integration, ThoughtSpot users didn’t have native connectivity to integrate Amazon Redshift with their identity providers (IdPs), which can provide unified governance and identity propagation across multiple AWS services like AWS Lake Formation and Amazon Simple Storage Service (Amazon S3).

Now, ThoughtSpot users can natively connect to Amazon Redshift using the IAM Identity Center integration, which streamlines data analytics access management while maintaining robust security. By configuring Amazon Redshift as an AWS managed application, organizations benefit from SSO capabilities with trusted identity propagation and a trusted token issuer (TTI). The IAM Identity Center integration with Amazon Redshift provides centralized user management, automatically synchronizing access permissions with organizational changes—whether employees join, transition roles, or leave the organization. The solution uses Amazon Redshift role-based access control features that align with IdP groups synced in IAM Identity Center. Organizations can further enhance their security posture by using Lake Formation to define granular access control permissions on catalog resources for IdP identities. From a compliance and security standpoint, the integration offers comprehensive audit trails by logging end-user identities both in Amazon Redshift and AWS CloudTrail, providing visibility into data access patterns and user activities.

Dime Dimovski, a Data Warehousing Architect at Merck, shares:

“The recent integration of Amazon Redshift with our identity access management center will significantly enhance our data access management because we can propagate user identities across various tools. By using OAuth authentication from ThoughtSpot to Amazon Redshift, we will benefit from a seamless single sign-on experience—giving us granular access controls as well as the security and efficiency we need.”

In this post, we walk you through the process of setting up ThoughtSpot integration with Amazon Redshift using IAM Identity Center authentication. The solution provides a secure, streamlined analytics environment that empowers your team to focus on what matters most: discovering and sharing valuable business insights.

Solution overview

The following diagram illustrates the architecture of the ThoughtSpot SSO integration with Amazon Redshift, IAM Identity Center, and your IdP.

The solution includes the following steps:

  1. The user configures ThoughtSpot to access Amazon Redshift using IAM Identity Center.
  2. When a user attempts to sign in, ThoughtSpot initiates a browser-based OAuth flow and redirects the user to their preferred IdP (such as Okta or Microsoft EntraID) sign-in page to enter their credentials.
  3. Following successful authentication, IdP issues authentication tokens (ID and access token) to ThoughtSpot.
  4. The Amazon Redshift driver then makes a call to the Amazon Redshift enabled AWS Identity Center application and forwards the access token.
  5. Amazon Redshift passes the token to IAM Identity Center for validation.
  6. IAM Identity Center first validates the token using the OpenID Connect (OIDC) discovery connection to the TTI and returns an IAM Identity Center generated access token for the same user. The TTI enables you to use trusted identity propagation with applications that authenticate outside of AWS. In the preceding figure, the IdP authorization server is the TTI.
  7. Amazon Redshift uses IAM Identity Center APIs to obtain the user and group membership information from AWS Identity Center.
  8. The ThoughtSpot user can now connect with Amazon Redshift and access data based on the user and group membership returned from IAM Identity Center.

In this post, you will use the following steps to build the solution:

  1. Set up an OIDC application.
  2. Set up a TTI in IAM Identity Center.
  3. Set up client connections and TTIs in Amazon Redshift.
  4. Federate to Amazon Redshift from ThoughtSpot using IAM Identity Center.

Prerequisites

Before you begin implementing the solution, you must have the following in place:

Set up an OIDC application

In this section, we’ll show you the step-by-step process to set up an OIDC application using both Okta and EntraID as the identity providers.

Set up an Okta OIDC application

Complete the following steps to set up an Okta OIDC application:

  1. Sign in to your Okta organization as a user with administrative privileges.
  2. On the admin console, under Applications in the navigation pane, choose Applications.
  3. Choose Create App Integration.
  4. Select OIDC – OpenID Connect for Sign-in method and Web Application for Application type.
  5. Choose Next.
  6. On the General tab, provide the following information:
    1. For App integration name, enter a name for your app integration. For example, ThoughtSpot_Redshift_App.
    2. For Grant type, select Authorization Code and Refresh Token.
    3. For Sign-in redirect URIs, choose Add URI and along with the default URI, add the URI https://<your_okta_instance_name>/callosum/v1/connection/generateTokens. The sign-in redirect URI is where Okta sends the authentication response and ID token for the sign-in request. The URIs must be absolute URIs.
    4. For Sign-out redirect URIs, keep the default value as http://localhost:8080.
    5. Skip the Trusted Origins section and for Assignments, select Skip group assignment for now.
    6. Choose Save.
  7. Choose the Assignments tab and then choose Assign to Groups. In this example, we’re assigning awssso-finance and awssso-sales.
  8. Choose Done.

Set up an EntraID OIDC application

To create your EntraID application, follow these steps:

  1. Sign in to the Microsoft Entra admin center as Cloud Application Administrator (or higher level of access).
  2. Browse to App registrations under Manage, and choose New registration.
  3. Enter a name for the application. For example, ThoughtSpot-OIDC-App.
  4. Select a supported account type, which determines who can use the application. For this example, select the first option in the list.
  5. Under Redirect URI, choose Web for the type of application you want to create. Enter the URI where the access token is sent to. Your redirect URL will be in the format https://<your_instance_name>/callosum/v1/connection/generateTokens.
  6. Choose Register.
  7. In the navigation pane, choose Certificates & secrets.
  8. Choose New client secret.
  9. Enter a description and select an expiration for the secret or specify a custom lifetime. For this example, keep the Microsoft recommended default expiration value of 6 months.
  10. Choose Add.
  11. Copy the secret value.

The secret value will only be presented one time; after that you can’t read it. Make sure to copy it now. If you fail to save it, you must generate a new client secret.

  1. In the navigation pane, under Manage, choose Expose an API.

If you’re setting up for the first time, you can see Add to the right of the application ID URI.

  1. Choose Save.
  2. After the application ID URI is set up, choose Add a scope.
  3. For Scope name, enter a name. For example, redshift_login.
  4. For Admin consent display name, enter a display name. For example, redshift_login.
  5. For Admin consent description, enter a description of the scope.
  6. Choose Add scope.
  7. In the navigation pane, choose API permissions.
  8. Choose Add a permission and choose Microsoft Graph.
  9. Choose Delegated Permission.
  10. Under OpenId permissions, choose email, offlines_access, openid, and profile, and choose Add permissions.

Set up a TTI in IAM Identity Center

Assuming you have completed the prerequisites, you will establish your IdP as a TTI in your delegated administration account. To create a TTI, refer to How to add a trusted token issuer to the IAM Identity Center console. In this post, we walk through the steps to set up a TTI for both Okta and EntraID.

Set up a TTI for Okta

To get the issuer URL from Okta, complete the following steps:

  1. Sign in as an admin to Okta and navigate to Security and then to API.
  2. Choose Default on the Authorization Servers tab and copy the Issuer
    url.
  3. In the Map attributes section, choose which IdP attributes correspond to Identity Center attributes. For example, in the following screenshot, we mapped Okta’s Subject attribute to the Email attribute in IAM Identity Center.
  4. Choose Create trusted token issuer.

Set up a TTI for EntraID

Complete the following steps to set up a TTI for EntraID:

  1. To find out which token your application is using, under Manage, choose Manifest.
  2. Locate the accessTokenAcceptedVersion parameter: null or 1 indicate v1.0 tokens, and 2 indicates v2.0 tokens.

Next, you need to find the tenant ID value from EntraID.

  1. Go to the EntraID application, choose Overview, and a new page will appear containing the Essentials
  2. You can find the tenant ID value as shown in the following screenshot. If you’re using the v1.0 token, the issuer URL will be https://sts.windows.net/<Directory (tenant) ID>/. If you’re using the v2.0 token, the issuer URL will be https://login.microsoftonline.com/<Directory (tenantid) ID>/v2.0.
  3. For Map attributes, the following example uses Other, where we’re specifying the user principal name (upn) as the IdP attribute to map with Email from the IAM identity Center attribute.
  4. Choose Create trusted token issuer.

Set up client connections and TTIs in Amazon Redshift

In this step, you configure the Amazon Redshift applications that exchange externally generated tokens to use the TTI you created in the previous step. Also, the audience claim (or aud claim) from your IdP must be specified. You need to collect the audience value from the respective IdP.

Acquire the audience value from Okta

To acquire the audience value from Okta, complete the following steps:

  1. Sign in as an admin to Okta and navigate to Security and then to API.
  2. Choose Default on the Authorization Servers tab and copy the Audience value.

Acquire the audience value from EntraID

Similarly, to get the audience value EntraID, complete the following steps:

  1. Go to the EntraID application, choose Overview, and a new page will appear containing the Essentials
  2. You can find the audience value (Application ID URI) as shown in the following screenshot.

Configure the application

After you collect the audience value from the respective IdP, you need to configure the Amazon Redshift application in the member account where the Amazon Redshift cluster or serverless instance exists.

  1. Choose IAM Identity Center connection in the navigation pane on the Amazon Redshift console.
  2. Choose the Amazon Redshift application that you created as part of the prerequisites.
  3. Choose the Client connections tab and choose Edit.
  4. Choose Yes under Configure client connections that use third-party IdPs.
  5. Select the check box for Trusted token issuer that you created in the previous section.
  6. For Aud claim, enter the audience claim value under Configure selected trusted token issuers.
  7. Choose Save.

Your IAM Identity Center, Amazon Redshift, and IdP configuration is complete. Next, you need to configure ThoughtSpot.

Federate to Amazon Redshift from ThoughtSpot using IAM Identity Center

Complete the following steps in ThoughtSpot to federate with Amazon Redshift using IAM Identity Center authentication:

  1. Sign in to ThoughtSpot cloud.
  2. Choose Data in the top navigation bar.
  3. Open the Connections tab in the navigation pane, and select the Redshift

Alternatively, you can choose Create new in the navigation pane, choose Connection, and select the Redshift tile.

  1. Create a name for your connection and a description (optional), then choose Continue.
  2. Under Authentication Type, choose AWS IDC OAuth and enter following details:
    1. For Host, enter the Redshift endpoint. For example, test-cluster.ab6yejheyhgf.us-east-1.redshift.amazonaws.com.
    2. For Port, enter 5439.
    3. For OAuth Client ID, enter the client ID from the IdP OIDC application.
    4. For OAuth Client Secret, enter the client secret from the IdP OIDC application.
    5. For Scope, enter the scope from the IdP application:
      • For Okta, use openid offline_access openid profile. You can use the Okta scope values shared earlier as is on ThoughtSpot. You can modify the scope according to your requirements.
      • For EntraID, use the API scope and API permissions. For example, api://1230a234-b456-7890-99c9-a12345bcc123/redshift_login offline_access.
    6. For API scope value, go to the OIDC application, and under Manage, choose Expose an API to acquire the value.
    7. For API permissions, go to the OIDC application, and under Manage, choose API permissions to acquire the permissions.
    8. For Auth Url, enter the authorization endpoint URI:
      • For Okta use https:// <okta-hostname>/oauth2/default/v1/authorize. For example, https://prod-1234567.okta.com/oauth2/default/v1/authorize.
      • For EntraID, use https://login.microsoftonline.com/<Directory (tenantid) ID>/oauth2/v2.0/authorize. For example, https://login.microsoftonline.com/e12a1ab3-1234-12ab-12b3-1a5012221d12/oauth2/v2.0/authorize.
    9. For Access token Url, enter the token endpoint URI:
      • For Okta, use https://<okta-hostname>/oauth2/default/v1/token. For example, https://prod-1234567.okta.com/oauth2/default/v1/token.
      • For EntraID, use https://login.microsoftonline.com/<Directory (tenantid) ID>/oauth2/v2.0/token. For example, https://login.microsoftonline.com/e12a1ab3-1234-12ab-12b3-1a5012221d12/oauth2/v2.0/token.
    10. For AWS Identity Namespace, enter the namespace configured in your Amazon Redshift IAM Identity Center application. The default value is AWSIDC unless previously customized. For this example, we use awsidc.
    11. For Database, enter the database name you want to connect. For example, dev.
  3. Choose Continue.
  4. Enter your IdP user credentials in the browser pop-up window.

The following screenshot illustrates the ThoughtSpot integration with Amazon Redshift using Okta as the IdP.

The following screenshot shows the ThoughtSpot integration with Amazon Redshift using EntraID as the IdP.

Upon a successful authentication, you will be redirected back to ThoughtSpot and logged in as an IAM Identity Center authenticated user.

Congratulations! You’ve logged in through IAM Identity Center and Amazon Redshift, and you’re ready to dive into your data analysis with ThoughtSpot.

Clean up

Complete the following steps to clean up your resources:

  1. Delete the IdP applications that you created to integrate with IAM Identity Center.
  2. Delete the IAM Identity Center configuration.
  3. Delete the Amazon Redshift application and the Amazon Redshift provisioned cluster or serverless instance that you created for testing.
  4. Delete the IAM role and IAM policy that you created for IAM Identity Center and Amazon Redshift integration.
  5. Delete the permission set from IAM Identity Center that you created for Amazon Redshift Query Editor V2 in the management account.
  6. Delete the ThoughtSpot connection to integrate with Amazon Redshift using AWS IDC OAuth.

Conclusion

In this post, we explored how to integrate ThoughtSpot with Amazon Redshift using IAM Identity Center. The process consisted of registering an OIDC application, setting up an IAM Identity Center TTI, and finally configuring ThoughtSpot for IAM Identity Center authentication. This setup creates a robust and secure analytics environment that streamlines data access for business users.

For additional guidance and detailed documentation, refer to the following key resources:


About the authors

Maneesh Sharma is a Senior Database Engineer at AWS with more than a decade of experience designing and implementing large-scale data warehouse and analytics solutions. He collaborates with various Amazon Redshift Partners and customers to drive better integration.

BP Yau is a Sr Partner Solutions Architect at AWS. His role is to help customers architect big data solutions to process data at scale. Before AWS, he helped Amazon.com Supply Chain Optimization Technologies migrate its Oracle data warehouse to Amazon Redshift and build its next generation big data analytics platform using AWS technologies.

Ali Alladin is the Senior Director of Product Management and Partner Solutions at ThoughtSpot. In this role, Ali oversees Cloud Engineering and Operations, ensuring seamless integration and optimal performance of ThoughtSpot’s cloud-based services. Additionally, Ali spearheads the development of AI-powered solutions in augmented and embedded analytics, collaborating closely with technology partners to drive innovation and deliver cutting-edge analytics capabilities. With a robust background in product management and a keen understanding of AI technologies, Ali is dedicated to pushing the boundaries of what’s possible in the analytics space, helping organizations harness the full potential of their data.

Debu Panda is a Senior Manager, Product Management at AWS. He is an industry leader in analytics, application platform, and database technologies, and has more than 25 years of experience in the IT world.

ML-KEM post-quantum TLS now supported in AWS KMS, ACM, and Secrets Manager

Post Syndicated from Alex Weibel original https://aws.amazon.com/blogs/security/ml-kem-post-quantum-tls-now-supported-in-aws-kms-acm-and-secrets-manager/

Amazon Web Services (AWS) is excited to announce that the latest hybrid post-quantum key agreement standards for TLS have been deployed to three AWS services. Today, AWS Key Management Service (AWS KMS), AWS Certificate Manager (ACM), and AWS Secrets Manager endpoints now support Module-Lattice-Based Key-Encapsulation Mechanism (ML-KEM) for hybrid post-quantum key agreement in non-FIPS endpoints in all AWS Regions in the aws partition. The AWS Secrets Manager Agent, built on AWS SDK for Rust now also has opt-in support for hybrid post-quantum key agreement. With this, customers can bring secrets into their applications with end-to-end post-quantum enabled TLS.

These three services were chosen because they are security-critical AWS services with the most urgent need for post-quantum confidentiality. These three AWS services have previously deployed support for CRYSTALS-Kyber, the predecessor of ML-KEM. Support for CRYSTALS-Kyber will continue through 2025, but will be removed across all AWS service endpoints in 2026 in favor of ML-KEM.

Our migration to post-quantum cryptography

AWS is committed to following our post-quantum cryptography migration plan. As part of this commitment, and part of the AWS post-quantum shared responsibility model, AWS plans to deploy support for ML-KEM to all AWS services with HTTPS endpoints over the coming years. AWS customers must update their TLS clients and SDKs to offer ML-KEM when connecting to AWS service HTTPS endpoints. This will protect against future harvest now, decrypt later threats posed by quantum computing advancements. Meanwhile, AWS service HTTPS endpoints will be responsible for selecting ML-KEM when offered by clients.

Our commitment to negotiate hybrid post-quantum key agreement algorithms is enabled by AWS Libcrypto (AWS-LC), our open-source FIPS-140-3-validated cryptographic library used throughout AWS, and s2n-tls, our open-source TLS implementation used across AWS service HTTPS endpoints. AWS-LC has been awarded multiple FIPS certificates from NIST (#4631, #4759, and #4816), and was the first open-source cryptographic module to include ML-KEM in a FIPS 140-3 validation.

The effect of hybrid post-quantum ML-KEM on TLS performance

Migrating from an Elliptic Curve Diffie-Hellman (ECDH)-only key agreement to an ECDH+ML-KEM hybrid key agreement necessarily requires that the TLS handshake send more data and perform more cryptographic operations. Switching from a classical to a hybrid post-quantum key agreement will transfer approximately 1600 additional bytes during the TLS handshake and will require approximately 80–150 microseconds more compute time to perform ML-KEM cryptographic operations. This is a one-time TLS connection startup cost and is amortized over the lifetime of the TLS connection across the HTTP requests sent over that connection.

AWS is working to provide a smooth migration to hybrid post-quantum key agreement for TLS. This work includes performing benchmarks on example workloads to help customers understand the impact of enabling hybrid post-quantum key agreement with ML-KEM.

Using the AWS SDK for Java v2, AWS has measured the number of AWS KMS GenerateDataKey requests per second that a single thread can issue serially between an Amazon Elastic Compute Cloud (Amazon EC2) C6in.metal client and the public AWS KMS endpoint. Both the client and server were in the us-west-2 Region. Classical TLS connections to AWS KMS negotiated the P256 elliptic curve for key agreement, and hybrid post-quantum TLS connections negotiated the X25519 elliptic curve with ML-KEM-768 for their hybrid key agreement. Your own performance characteristics might differ and will depend on your environment, including your instance type, your workload profiles, the amount of parallelism and number of threads used, and your network location and capacity. The HTTP request transaction rates were measured with TLS connection reuse both enabled and disabled.

Figure 1 shows the number of requests per second issued at different percentiles when TLS 1.3 connection reuse is disabled. It shows that in the worst-case scenario—when the cost of a TLS handshake is never amortized and every HTTP request must perform a full TLS handshake—enabling hybrid post-quantum TLS decreases the transactions per second (TPS) by about 2.3 percent on average, from 108.7 TPS to 106.2 TPS.

Figure 1: AWS KMS GenerateDataKey requests per second <em>without</em> TLS connection reuse” width=”1747″ height=”1221″ class=”size-full wp-image-37873″ style=”border: 1px solid #bebebe”></p>
<p id=Figure 1: AWS KMS GenerateDataKey requests per second without TLS connection reuse

Figure 2 shows the number of requests per second issued at different percentiles when TLS connection reuse is enabled. Reusing TLS connections and amortizing the cost of a TLS handshake over many HTTP requests is the default setting in the AWS SDK for Java v2. We show that enabling hybrid post-quantum TLS when using default SDK settings leaves the TPS rate almost unchanged, with only a 0.05 percent decrease on average, from 216.1 TPS to 216.0 TPS.

Figure 2: AWS KMS GenerateDataKey requests per second <em>with</em> TLS connection reuse” width=”1747″ height=”1226″ class=”size-full wp-image-37874″ style=”border: 1px solid #bebebe”></p>
<p id=Figure 2: AWS KMS GenerateDataKey requests per second with TLS connection reuse

Our results show that the performance impact of enabling hybrid post-quantum TLS is negligible when using typical configuration settings in your SDK. Our measurements show that enabling hybrid post-quantum TLS for a default-case example workload only lowered maximum TPS rate by 0.05 percent. Our results also show that overriding SDK defaults to force the worst-case scenario of performing a new TLS handshake for every request only decreased maximum TPS rate by 2.3 percent.

The following table shows the benchmark data that we measured. Each benchmark performed 500 one-second TPS measurements for varying TLS key agreement settings and TLS connection reuse settings. The measurements used v2.30.22 of the AWS SDK for Java v2. The TLS key agreement was switched between classical and hybrid post-quantum by toggling the postQuantumTlsEnabled() configuration. TLS connection reuse was toggled by injecting a Connection: close HTTP header into each HTTP request. This header forces the TLS connection to be shut down after each HTTP request and requires that a new TLS connection be created for each HTTP request.

TLS key agreement TLS conn resuse Total HTTP requests Average (TPS) p01 (TPS) p10 (TPS) p25 (TPS) p50 (TPS) p75 (TPS) p90 (TPS) p99 (TPS)
Classical (P256) No 54,367 108.7 78 86 96 102 129 137 145
Hybrid post-quantum (X25519MLKEM768) No 53,106 106.2 76 85 93 100 126 134 141
Classical (P256) Yes 108,052 216.1 181 194 200 216 233 240 245
Hybrid post-quantum (X25519MLKEM768) Yes 107,994 216 177 194 200 216 233 239 245

Removing support for draft post-quantum standards

AWS service endpoints with support for CRYSTALS-Kyber, the predecessor of ML-KEM, will continue to support CRYSTALS-Kyber through 2025. We will slowly phase out support for the pre-standard CRYSTALS-Kyber implementations after customers have moved to the ML-KEM standard. Customers using previous versions of the AWS SDK for Java with CRYSTALS-Kyber support should upgrade to the latest SDK versions that have ML-KEM support. No code changes are necessary for customers using a generally available release of the AWS SDK for Java v2 to upgrade from CRYSTALS-Kyber to ML-KEM.

Customers currently negotiating CRYSTALS-Kyber who do not upgrade their AWS Java SDK v2 clients by 2026 will see their clients gracefully fall back to a classical key agreement once CRYSTALS-Kyber is removed from AWS service HTTPS endpoints.

How to use hybrid post-quantum key agreement

If using the AWS SDK for Rust, you can enable the hybrid post-quantum key agreement by adding the rustls package to your crate and enabling the prefer-post-quantum feature flag. See the rustls documentation for more information.

If using the AWS SDK for Java 2.x, you can enable hybrid post-quantum key agreement by calling .postQuantumTlsEnabled(true) when building your AWS Common Runtime HTTP client.

Step 1: Add the AWS Common Runtime HTTP client to your Java dependencies.

Add the AWS Common Runtime HTTP client to your Maven dependencies. We recommend using the latest available version. Use version 2.30.22 or greater to enable the use of ML-KEM.

<dependency>
    <groupId>software.amazon.awssdk</groupId>
    <artifactId>aws-crt-client</artifactId>
    <version>2.30.22<version>
</dependency>

Step 2: Enable post-quantum TLS in your Java SDK client configuration

When configuring your AWS service client, use the AwsCrtAsyncHttpClient configured with post-quantum TLS.

// Configure an AWS Common Runtime HTTP client with Post-Quantum TLS enabled
SdkAsyncHttpClient awsCrtHttpClient = AwsCrtAsyncHttpClient.builder()
          .postQuantumTlsEnabled(true)
          .build();

// Create an AWS service client that uses the AWS Common Runtime client
KmsAsyncClient kmsAsync = KmsAsyncClient.builder()
         .httpClient(awsCrtHttpClient)
         .build();

// Make a request over a TLS connection that uses post-quantum key agreement
ListKeysReponse keys = kmsAsync.listKeys().get();

See the KMS PQ TLS example application for an end-to-end example of a post-quantum TLS setup.

Things to try

Here are some ideas about how to use this post-quantum-enabled client:

  • Run load tests and benchmarks. The AwsCrtAsyncHttpClient is heavily optimized for performance and uses AWS Libcrypto on Linux-based environments. If you aren’t already using the AwsCrtAsyncHttpClient, try it today to see the performance benefits compared to the default SDK HTTP client. After using AwsCrtAsyncHttpClient, enable post-quantum TLS support. See if using AwsCrtAsyncHttpClient with post-quantum TLS is an overall performance gain to using the default SDK HTTP client without post-quantum TLS.
  • Try connecting from different network locations. Depending on the network path that your request takes, you might discover that intermediate hosts, proxies, or firewalls with deep packet inspection (DPI) block the request. If this is the case, you might need to work with your security team or IT administrators to update firewalls in your network to unblock these new TLS algorithms. We want to hear from you about how your infrastructure interacts with this new variant of TLS traffic.

Conclusion

Support for ML-KEM-based hybrid key agreement has been deployed to three security-critical AWS service endpoints. The performance impact of enabling hybrid post-quantum TLS is likely to be negligible when TLS connection reuse is enabled. Our measurements showed only a 0.05 percent decrease to maximum transactions per second when calling AWS KMS GenerateDataKey.

Starting with version 2.30.22, the AWS SDK for Java v2 now supports ML-KEM-based hybrid key agreement on Linux-based platforms when using the AWS Common Runtime HTTP client. Try enabling post quantum key agreement for TLS in your Java SDK client configuration today.

AWS plans to deploy support for ML-KEM-based hybrid post-quantum key agreement to every AWS service HTTPS endpoint over the coming years as part of our post-quantum cryptography migration plan. AWS customers will be responsible for updating their TLS clients and SDKs to help ensure that ML-KEM key agreement is offered when connecting to AWS service HTTPS endpoints. This will protect against future harvest now, decrypt later threats posed by quantum computing advancements.

For additional information, blog posts, and periodic updates on our post-quantum cryptography migration, keep watching the AWS Post-Quantum Cryptography page. To learn more about post-quantum cryptography with AWS, contact the post-quantum cryptography team.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Security, Identity, & Compliance re:Post or contact AWS Support.

Additional resources:

If you have feedback about this post, submit comments in the Comments section below.

Author

Alex Weibel

Alex is a Senior Software Development Engineer in AWS Cryptography. He’s a contributor to the Amazon TLS Library s2n-tls, the Amazon Corretto Crypto Provider (ACCP), and AWS Libcrypto (AWS-LC). Previously, Alex worked on TLS termination and HTTP request proxying for Amazon S3 and Elastic Load Balancing, developing new features for customers. Alex holds a Bachelor of Science degree in Computer Science from the University of Texas at Austin.

Correlate telemetry data with Amazon OpenSearch Service and Amazon Managed Grafana

Post Syndicated from Balaji Mohan original https://aws.amazon.com/blogs/big-data/correlate-telemetry-data-with-amazon-opensearch-service-and-amazon-managed-grafana/

Troubleshooting a large, complex, distributed enterprise application involves challenges like tracing requests across multiple services, identifying performance bottlenecks across the stack, and understanding cascading failures between dependent services. Customers often need to work with isolated data to identify the underlying cause of the problem. By correlating different signals like logs, traces, metrics, and other performance indicators, you can get valuable insight into what caused the problem, where, and why.

Amazon OpenSearch Service is a managed service to deploy, operate, and search data at scale within AWS. Amazon Managed Grafana is a secure data visualization service to query operational data from multiple sources, including OpenSearch Service.

In this post, we show you how to use these services to correlate the various observability signals that improve root cause analysis, thereby resulting in reduced Mean Time to Resolution (MTTR). We also provide a reference solution that can be used at scale for proactive monitoring of enterprise applications to avoid a problem before they occur.

Solution overview

The following diagram shows the solution architecture for collecting and correlating various enterprise telemetry signals at scale.

At the core of this architecture are applications composed of microservices (represented by orange boxes) running on Amazon Elastic Kubernetes Service (Amazon EKS). These microservices contain instrumentation that emit telemetry data in the form of metrics, logs, and traces. This data is exported into the OpenTelemetry Collector, which serves as a central vendor agnostic gateway to collect this data uniformly.

In this post, we use an OpenTelemetry demo application as a sample enterprise application. Large enterprise customers typically separate their observability signal data into various stores for scalability, fault isolation, access control, and ease of operation. To aid in these functions, we recommend and use Amazon OpenSearch Ingestion for a serverless, scalable, and fully managed data pipeline. We separate log and trace data and send them to distinct OpenSearch Service domains. The solution also sends the metrics data to Amazon Managed Service for Prometheus.

We use Amazon Managed Grafana as a data visualization and analytics platform to query and visualize this data. We also show how to employ correlations as a valuable tool to gain insights from these signals spread across various data stores.

The following sections outline building this architecture at scale.

Prerequisites

Complete the following prerequisite steps:

  1. Provision and configure the Amazon Managed Prometheus workspace to receive metrics from the OpenTelemetry Collector.
  2. Create two dedicated OpenSearch Service domains (or use existing ones) to ingest logs and traces from the OpenTelemetry Collector.
  3. Create an Amazon Managed Grafana workspace and configure data sources to connect to Amazon Managed Prometheus and OpenSearch Service.
  4. Set up an EKS cluster to deploy applications and the OpenTelemetry Collector.

Create log and trace OpenSearch Ingestion pipelines

Before setting up the ingestion pipelines, you need to create the necessary AWS Identity and Access Management (IAM) policies and roles. This process involves creating two policies for domain and OSIS access, followed by creating a pipeline role that uses these policies.

Create a policy for ingestion

Complete the following steps to create an IAM policy:

  1. Open the IAM console.
  2. Choose Policies in the navigation pane, then choose Create policy.
  3. On the JSON tab, enter the following policy into the editor:
{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": "es:DescribeDomain",
            "Resource": "arn:aws:es:*:{accountId}:domain/*"
        },
        {
            "Effect": "Allow",
            "Action": [ "es:ESHttpGet", "es:HttpHead", "es:HttpDelete", "es:HttpPatch", "es:HttpPost", "es:HttpPut" ],
            "Resource": "arn:aws:es:us-east-1:{accountId}:domain/otel-traces"
        },
        {
            "Effect": "Allow",
            "Action": [ "es:ESHttpGet", "es:HttpHead", "es:HttpDelete", "es:HttpPatch", "es:HttpPost", "es:HttpPut" ],
            "Resource": "arn:aws:es:us-east-1:{accountId}:domain/otel-logs"
        }
        }
    ]
}

// Replace {accountId} with your own values
  1. Choose Next, choose Next again, and name your policy domain-policy.
  2. Choose Create policy.
  3. Create another policy with the name osis-policy and use the following JSON:
{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": "osis:Ingest",
            "Resource": "arn:aws:osis:us-east-1:{accountId}:pipeline/osi-pipeline-otellogs"
        },
        {
            "Effect": "Allow",
            "Action": "osis:Ingest",
            "Resource": "arn:aws:osis:us-east-1:{accountId}:pipeline/osi-pipeline-oteltraces"
        }
    ]
}
// Replace {accountId} with your own values

Create a pipeline role

Complete the following steps to create a pipeline role:

  1. On the IAM console, choose Roles in the navigation pane, then choose Create role.
  2. Select Custom trust policy and enter the following policy into the editor:
{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Principal": {
                "Service": [
                    "eks.amazonaws.com",
                    "osis-pipelines.amazonaws.com"
                ],
                "AWS": "{nodegroup_arn}"
            },
            "Action": "sts:AssumeRole"
        }
    ]
}

// Replace {nodegroup_arn} with your own values
  1. Choose Next, then search for and select the policies osis-policy and domain-policy you just created.
  2. Choose Next and name the role PipelineRole.
  3. Choose Create role.

Allow access for the pipeline role in OpenSearch Service domains

To enable access for the pipeline role in OpenSearch Service domains, complete the following steps:

  1. Open the OpenSearch Service console.
  2. Choose your domain (either logs or traces).
  3. Choose the OpenSearch Dashboards URL
  4. Sign in with your credentials.

Then, complete the following steps for each OpenSearch Service domain (logs and traces domains).

  1. In OpenSearch Dashboards, go to the Security
  2. Choose Roles and then all_access.

This procedure uses the all_access role for demonstration purposes only. This grants full administrative privileges to the pipeline role, which violates the principle of least privilege and could pose security risks. For production environments, you should create a custom role with minimal permissions required for data ingestion, limit permissions to specific indexes and operations, consider implementing index patterns and time-based access controls, and regularly audit role mappings and permissions. For detailed guidance on creating custom roles with appropriate permissions, refer to Security in Amazon OpenSearch Service.

  1. Choose Mapped users and then Managed mapping.
  2. On the Map user page, under Backend roles, update the backend role with the Amazon Resource Name (ARN) for the role PiplelineRole.
  3. Choose Map.

Create a pipeline for logs

Complete the following steps to create a pipeline for logs:

  1. Open the OpenSearch Service console.
  2. Choose Ingestion pipelines.
  3. Choose Create pipeline.
  4. Define the pipeline configuration by entering the following:
version: "2"
otel-logs-pipeline:
  source:
    otel_logs_source:
      path: "/v1/logs"
  sink:
    - opensearch:
        hosts: ["{OpenSearch_domain_endpoint}"]
        aws:
          sts_role_arn: "arn:aws:iam::{accountId}:role/osi-pipeline-role"
          region: "us-east-1"
          serverless: false
        index: "observability-otel-logs%{yyyy-MM-dd}"
       
 # To get the values for the placeholders:
 # 1. {OpenSearch_domain_endpoint}: You can find the domain endpoint by navigating to the Amazon Managed Opensearch managed clusters in the AWS Management Console, and then clicking on the domain.
 # After obtaining the necessary values, replace the placeholders in the configuration with the actual values.           

Create a pipeline for traces

Complete the following steps to create a pipeline for traces:

  1. Open the OpenSearch Service console.
  2. Choose Ingestion pipelines.
  3. Choose Create pipeline.
  4. Define the pipeline configuration by entering the following:
version: "2"
entry-pipeline:
  source:
    otel_trace_source:
      path: "/v1/traces"
  processor:
    - trace_peer_forwarder:
  sink:
    - pipeline:
        name: "span-pipeline"
    - pipeline:
        name: "service-map-pipeline"
span-pipeline:
  source:
    pipeline:
      name: "entry-pipeline"
  processor:
    - otel_traces:
  sink:
    - opensearch:
        index_type: "trace-analytics-raw"
        hosts: ["{OpenSearch_domain_endpoint}"]
        aws:                 
          sts_role_arn: "arn:aws:iam::{accountId}:role/osi-pipeline-role"
          region: "us-east-1"
service-map-pipeline:
  source:
    pipeline:
      name: "entry-pipeline"
  processor:
    - service_map:
  sink:
    - opensearch:
        index_type: "trace-analytics-service-map"
        hosts: ["{OpenSearch_domain_endpoint}"]
        aws:                 
          sts_role_arn: "arn:aws:iam::{accountId}:role/osi-pipeline-role"
          region: "us-east-1"
         
 # To get the values for the placeholders:
 # 1. {OpenSearch_domain_endpoint}: You can find the domain endpoint by navigating to the Amazon Managed Opensearch managed clusters in the AWS Management Console, and then clicking on the domain.  # 2. {accountId}: This is your AWS account ID. You can find your account ID by clicking on your username in the top-right corner of the AWS Management Console and selecting "My Account" from the dropdown menu.
 # After obtaining the necessary values, replace the placeholders in the configuration with the actual values.     

Install the OpenTelemetry demo application in Amazon EKS

Use the EKS cluster you set up earlier along with AWS CloudShell or another tool to complete these steps:

  1. Open the AWS Management Console.
  2. Choose the CloudShell icon in the top navigation bar, or go directly to the CloudShell console.
  3. Wait for the shell environment to initialize—it comes preinstalled with common AWS Command Line Interface (AWS CLI) tools.

Now you can complete the following steps to install the application.

  1. Clone the OpenTelemetry Demo repository:
git clone https://github.com/aws-samples/sample-correlation-opensearch-repository
  1. Navigate to the Kubernetes directory:
cd deployment_files
  1. Deploy the demo application using kubectl apply:
kubectl apply -f .
  1. Use a load balancer to expose the frontend service so you can reach the source application web URL:
kubectl expose deployment opentelemetry-demo-frontendproxy --type=LoadBalancer --name=frontendproxy
  1. After you have deployed the application, access the frontend application using the load balancer on port 8080. Use your browser to visit http://<LoadBalancerIP>:8080/ to open the source application for OpenTelemetry.

By following these steps, you can successfully install and access demo applications on your EKS cluster.

Configure the OpenTelemetry Collector exporter for logs, traces, and metrics

The OpenTelemetry Collector is a tool that manages the receiving, processing, and exporting of telemetry data from your application to a target repository.

In this step, we send logs and traces to OpenSearch Service and metrics to Amazon Managed Prometheus. The OpenTelemetry Collector also works with popular data repositories like Jaeger and a variety of other open source and commercial platforms. In this section, we include steps to configure the OpenTelemetry Collector in an EKS environment. Then we deploy the demo application and explore the OpenTelemetry exporters using AWS Managed Solutions instead of the open source versions.

Complete the following steps:

  1. Open the otel-collector-config ConfigMap in your preferred editor:
kubectl edit configmap opentelemetry-demo-otelcol -n otel-demo
  1. Update the exporters section with the following configuration (provide the appropriate Amazon Managed Service for Prometheus endpoint and OpenSearch Service log ingestion URLs):
exporters:
     logging: {}
     otlphttp/logs:
       logs_endpoint: "<AWS_OPENSEARCH_LOG_INGESTION_URL>/v1/logs"
       auth:
         authenticator: sigv4auth
       compression: none
     otlphttp/traces:
       traces_endpoint: "<AWS_OPENSEARCH_TRACE_INGESTION_URL>/v1/traces"
       auth:
         authenticator: sigv4auth
       compression: none
     prometheusremotewrite:
        endpoint: "<AWS_MANAGED_PROMETHEUS_ENDPOINT>"
        auth:
          authenticator: sigv4auth 
  1. Locate the extensions section and update the IAM role ARN in the sigv4auth configuration:
sigv4auth:
        assume_role:
            arn: "arn:aws:iam::{accountId}:role/osi-pipeline-role"
            sts_region: "us-east-1"
        region: "us-east-1"
        service: "osis"
 #  {accountId}: replace accountID with your account id
  1. After updating the ConfigMap, restart the OpenTelemetry Collector deployment:
kubectl rollout restart deployment opentelemetry-demo-otelcol -n otel-demo

With these changes, the OpenTelemetry Collector will send trace data to the OpenSearch Service domain, metrics data to the AWS Managed Service for Prometheus endpoint, and log data to the OpenSearch Service domain.

Configure Amazon Managed Grafana

Before you can visualize your logs and traces, you need to configure OpenSearch Service as a data source in your Amazon Managed Grafana workspace. This configuration is done through the Amazon Managed Grafana console.

Configure the OpenSearch Service data source

Complete the following steps to configure the OpenSearch Service data source:

  1. Open the Amazon Managed Grafana console.
  2. Select your workspace and choose the workspace URL to access your Grafana instance.
  3. Log in to your Amazon Managed Grafana instance.
  4. From the side menu, choose the configuration (gear) icon.
  5. On the Configuration menu, choose Data Sources.
  6. Choose Add data source.
  7. On the Add data source page, select OpenSearch Service from the list of available data sources.
  8. In the Name field, enter a descriptive name for the data source.
  9. In the URL field, enter the URL (OpenSearch Service domain endpoint) of your OpenSearch Service domain, including the protocol and port number.
  10. If your OpenSearch cluster is configured with authentication, provide the required credentials in the User and Password
  11. If you want to use a specific index pattern for the data source, you can specify it in the Index name field (For example, logstash-*).
  12. Adjust any other settings as needed, such as the Time field name and Time interval.
  13. Choose Save & Test to verify the connection to your OpenSearch cluster.

If the test is successful, you should see a green notification with the message “Data source is working.”

  1. Choose Save to save the data source configuration.
  2. Repeat the same steps for the OpenSearch logs and traces domains.

Configure the Prometheus data source

Complete the following steps to configure the Prometheus data source:

  1. Open the Amazon Managed Grafana console.
  2. Select your workspace and choose the workspace URL to access your Grafana instance.
  3. Log in to your Amazon Managed Grafana instance.
  4. From the side menu, choose the configuration (gear) icon.
  5. On the Configuration menu, choose Data Sources.
  6. Choose Add data source.
  7. On the Add data source page, select Amazon Managed Prometheus from the list of available data sources.
  8. In the Name field, enter a descriptive name for the data source.
  9. The AWS Auth Provider and Default Region fields should be automatically populated based on your Amazon Managed Grafana workspace configuration.
  10. In the Workspace field, enter the ID or alias of your Amazon Managed Prometheus workspace.
  11. Choose Save & Test to verify the connection to your Amazon Managed Prometheus workspace.

If the test is successful, you should see a green notification with the message “Data source is working.”

  1. Choose Save to save the data source configuration.

Create correlations in Amazon Managed Grafana

To establish connections between your logs and traces data, you need to set up data correlations in Amazon Managed Grafana. This allows you to navigate seamlessly between related logs and traces. Follow these steps in your Amazon Managed Grafana workspace:

  1. Open the Amazon Managed Grafana console.
  2. Select your workspace and choose the workspace URL to access your Grafana instance.
  3. In the Amazon Managed Grafana portal, on the Administration menu, choose Plugins and Data, and choose Correlation.

  1. On the Set up the target for the correlation page, under Target, choose your traces data source (OpenSearch Service, for example, otel-traces) from the dropdown list and define the query that will execute when the link is followed. You can use variables to query specific field values. For example, traceId: ${__value.raw}.

  1. On the Set up the target for the correlation page, choose the log data source from the dropdown list, and enter the field name to be linked or correlated with the traces data source in the OpenSearch Service data source. For example, traceID.

  1. Choose Save to complete the correlation configuration.

  1. Repeat the steps to create a correlation between metrics on Prometheus to logs in OpenSearch Service.

Validate results

In Amazon Managed Grafana, using the Prometheus data source, locate the desired instance for correlation. The instance ID will be displayed as a link. Follow the link to open the corresponding log details in a panel on the right side of the page.

With the logs to traces correlation configured, you can access trace information directly from the logs page. Choose traces on the log details panel to view the corresponding trace data.

The following screenshot demonstrates the node graph visualization showing the correlation flow: instance metrics to logs to traces.

Clean up

Remove the infrastructure for this solution when not in use to avoid incurring unnecessary costs.

Conclusion

In this post, we showed how to use correlation as a helpful tool to gain insight into observability data stored in various stores.

Separating logs and traces into dedicated domains provides the following benefits:

  • Better resource allocation and scaling based on different workload patterns
  • Independent performance optimization for each data type
  • Simplified cost tracking and management
  • Enhanced security control with separate access policies

You can use this solution as a reference to build a scalable observability solution for your enterprise to detect, investigate, and remediate problems faster. This ability, when used along next-generation artificial intelligence and machine learning (AI/ML), helps to not only proactively react but predict and prevent problems before they occur. You can learn more about AI/ML with AWS.


About the Authors

Balaji Mohan is a Senior Delivery Consultant specializing in application and data modernization to the cloud. His business-first approach provides seamless transitions, aligning technology with organizational goals. Using cloud-centered architectures, he delivers scalable, agile, and cost-effective solutions, driving innovation and growth.

Senthil Ramasamy is a Senior Database Consultant at Amazon Web Services. He works with AWS customers to provide guidance and technical assistance on database services, helping them with database migrations to the AWS Cloud and improving the value of their solutions when using AWS.

Muthu Pitchaimani is a Search Specialist with Amazon OpenSearch Service. He builds large-scale search applications and solutions. Muthu is interested in the topics of networking and security, and is based out of Austin, Texas.

Validate Your Lambda Runtime with CloudFormation Lambda Hooks

Post Syndicated from Matteo Luigi Restelli original https://aws.amazon.com/blogs/devops/validate-your-lambda-runtime-with-cloudformation-lambda-hooks/

Introduction

This post demonstrates how to leverage AWS CloudFormation Lambda Hooks to enforce compliance rules at provisioning time, enabling you to evaluate and validate Lambda function configurations against custom policies before deployment. Often these policies impact the way a software should be built, restricting language versions and runtimes. A great example is applying those policies on AWS Lambda, a serverless compute service for running code without having to provision or manage servers. While AWS Lambda already manages the deprecation of runtimes, preventing you from deploying unsupported runtimes, organizations may need to provide and enforce their specific compliance rules not directly linked to the deprecation of a specific language version.

Introducing Lambda Hooks

AWS CloudFormation Lambda Hooks are a powerful feature that allows developers to evaluate CloudFormation and AWS Cloud Control API operations against custom code implemented as Lambda functions. This capability enables proactive inspection of resource configurations before provisioning, enhancing security, compliance, and operational efficiency.

Lambda Hooks provide a mechanism to intercept and evaluate various CloudFormation operations, including resource operations, stack operations, and change set operations (they can also be used with Cloud Control API, but in this post we’re focusing on CloudFormation). By activating a Lambda Hook, CloudFormation creates an entry in your account’s registry as a private Hook, allowing you to configure it for specific AWS accounts and regions. When configuring Lambda Hooks, you can specify one or more Lambda functions to be invoked during the evaluation process. These functions can be in the same AWS account and Region as the Hook, or in another Account you own, provided proper permissions are set up. The evaluation process occurs at specific points in the CloudFormation Stack lifecycle. For instance, during stack creation, update, or deletion, the configured Lambda functions are invoked to assess the proposed changes against your defined compliance rules. Based on the evaluation results, the hook can either block the operation or issue a warning, allowing the operation to proceed.

Lambda Hooks evaluate resources before they are provisioned through CloudFormation, providing a pre-emptive layer of governance. This means that non-compliant resources are caught and prevented from being deployed, rather than requiring retroactive fixes. By leveraging Lambda Hooks, organizations can automate and standardize their compliance checks across all AWS accounts and regions. This centralized approach to policy enforcement ensures consistency and reduces the overhead of managing compliance manually.

Solution Overview

The following sections demonstrate a practical use case for AWS CloudFormation Lambda Hooks, focusing on enforcing compliance rules on AWS Lambda runtimes.

Meet AnyCompany, a forward-thinking enterprise with a robust set of compliance rules governing their software development practices. Among these rules is a strict policy on the use of specific AWS Lambda runtimes.

As they continue to embrace serverless architecture, AnyCompany faces a challenge: how to prevent the deployment of Lambda functions that use non-compliant runtimes. Given their commitment to AWS CloudFormation for deploying Lambda functions, AnyCompany is keen to leverage the power of AWS CloudFormation Lambda Hooks.

We’ll explore the setup process, demonstrate the hook in action, and discuss the broader implications for maintaining compliance in a dynamic cloud environment.

Architecture

The following architecture highlights the implementation of the Lambda Hook. In this implementation, we are using AWS CloudFormation Lambda Hooks to intercept the deployment of Lambda Functions and perform the compliance checks on these resources. The Lambda Hook will interact with an AWS Lambda Function, which will perform the compliance checks. Finally, we’re using AWS Systems Manager Parameter Store to store the Configuration Parameter which contains the list of permitted Lambda Runtimes.

Figure 1: Architecture of the Solution

Figure 1: Architecture of the Solution

  1. A Developer (or a CI/CD pipeline) deploys a CloudFormation stack containing Lambda functions.
  2. CloudFormation invokes the respective Lambda Hook, which is configured to intercept operations on AWS Lambda Resources. We are setting this hook to “FAIL” deployment in case checks are not successful.
  3. The Lambda Hook checks if the runtime of the Lambda is admitted or violates Company’s compliance. To do this, it checks if the runtime is present on a pre-configured list of admitted runtimes saved as Parameter in AWS Systems Manager Parameter Store. Keep in mind that we’re using SSM Parameter Store to store the configuration for this specific example, but other alternatives may be viable as well (Amazon DynamoDB, AWS Secrets Manager, or AppConfig lambda-function-settings-check Preventive Rule)
  4. The Lambda Hook, after checking runtime compliance, replies:
    • With a failure, if the Lambda runtime is not compliant
    • With a success, if the Lambda runtime is compliant
  5. Depending on the response of the Lambda Hook, the deployment may or not take place.

Repository Structure

You can find all the code for this solution at this link. Here’s the repository structure:

.
├── README.md
├── deploy.sh
├── cleanup.sh
├── hook-lambda
│ ├── index.ts
│ ├── package.json
│ ├── services
│ │ └── parameter-store.ts
│ └── tsconfig.json
├── sample
│ ├── deploy_sample.sh
│ ├── cleanup_sample.sh
│ └── lambda_template.yml
└── template.yml
  • hook-lambda: directory containing all the code related to the CloudFormation Lambda Hook (Validation Lambda Function, and the CloudFormation template for the Solution)
  • sample: directory containing the code of the sample used to test the CloudFormation Lambda Hook
  • deploy.sh: utility script to deploy the Solution via AWS CLI
  • cleanup.sh: utility script to clean up the AWS CloudFormation Hook infrastructure via the AWS CLI
  • template.yml: AWS CloudFormation Template containing all the AWS Resources involved in the Solution

Prerequisites

You must have the following prerequisites for this solution:

  • An AWS account or sign up to create and activate one.
  • The following software installed on your development machine:
  • Install the AWS Command Line Interface (AWS CLI) and configure it to point to your AWS account.
  • Install Node.js and use a package manager such as npm.
  • Appropriate AWS credentials for interacting with resources in your AWS account.

Walkthrough

Creating the AWS Lambda Validation Function – Lambda Code

The CloudFormation Lambda Hook interacts with a specific Lambda (referred to as Validation Lambda throughout the rest of this post), which gets invoked during CloudFormation CREATE and UPDATE STACK operations involving Lambda Functions. The goal is to check if these Lambda functions have runtimes that comply with AnyCompany’s rules.

Below is the detailed description of the steps that the Validation Lambda function handler follows (the code is written in Typescript).

First, the Validation Lambda retrieves an environment variable containing the SSM Parameter Store parameter name which contains the compliant runtimes list. Additionally, safety checks ensure that only Lambda Resources are considered and that their Runtime property is defined.

Note that both safety checks could be skipped, since the Hook should already be configured to interact only with Lambda Resources and the Lambda’s Runtime property is always required. However, they remain in place to demonstrate how to retrieve this information from the Lambda Hook event in your handler.

const parameterName = process.env.PERMITTED_RUNTIMES_PARAM;
if (!parameterName) {
	throw new Error('Permitted Runtimes Parameter is not set');
}

const resourceProperties = event.requestData.targetModel.resourceProperties;
// Check if this is a Lambda function resource
if (event.requestData.targetType !== 'AWS::Lambda::Function') {
console.log("Resource is not a Lambda function, skipping");
	return {
		hookStatus: 'SUCCESS',
		message: 'Not a Lambda function resource, skipping validation',
		clientRequestToken: event.clientRequestToken
	}
}

// Check runtime version compliance
const runtime = resourceProperties.Runtime;
if (!runtime) {
	console.log("Runtime not defined, failing");
	return {
		hookStatus: 'FAILURE',
		errorCode: 'NonCompliant',
		message: 'Runtime is required for Lambda functions',
		clientRequestToken: event.clientRequestToken
	}
}

Then the Validation Lambda retrieves the value of the Configuration Parameter from SSM Parameter Store through a utility class called ParameterStoreService. For this post, consider that the value inside that Configuration Parameter is a list of strings, where each string contains one of the possible Lambda runtime values that you can find here (e.g. nodejs22.x,nodejs20.x,python3.11,python3.10,java17,java11,dotnet6). After retrieving the value, the Validation Lambda checks if the runtime of the Lambda Resource complies with the configured admitted runtimes. If the runtime is not compliant, you’ll receive a properly formatted response with FAILURE as hookStatus, otherwise the response will contain a SUCCESS hookStatus.

// Retrieve configuration from Parameter Store
const compliantRuntimes = await parameterStoreService.getParameterFromStore(parameterName);

// Check if Lambda runtime is permitted or not
if (!compliantRuntimes.includes(runtime)) {
console.log("Runtime " + runtime + " not compliant ");
	return {
		hookStatus: 'FAILURE',
		errorCode: 'NonCompliant',
		message: `Runtime ${runtime} is not compliant. Please use one of: ${compliantRuntimes.join(', ')}`,
		clientRequestToken: event.clientRequestToken
	}
}

return {
	hookStatus: 'SUCCESS',
	message: 'Runtime version compliance check passed',
	clientRequestToken: event.clientRequestToken
}

For more information about the possible response values of CloudFormation Lambda Hooks Lambda, have a look at this link.

Creating the validation Lambda – Lambda CloudFormation definition

The Validation Lambda function will be deployed via CloudFormation, in the same Stack with the CloudFormation Lambda Hook definition and the AWS Systems Manager Parameter Store Parameter. Here’s the fragment of the CloudFormation Template containing its definition:

# Lambda Function
ValidationFunction:
	Type: AWS::Lambda::Function
	Properties:
		Handler: index.handler
		Role: !GetAtt LambdaExecutionRole.Arn
		Code:
			S3Bucket: !Ref DeploymentBucket
			S3Key: hook-lambda.zip
		Runtime: nodejs22.x
		Timeout: 60
		MemorySize: 128
		Environment:
			Variables:
				PERMITTED_RUNTIMES_PARAM: !Ref ParameterStoreParamName

You’ll need to associate an IAM Role with proper permissions to access the AWS Systems Manager Parameter Store Parameter:

# Lambda Function Role
LambdaExecutionRole:
    Type: AWS::IAM::Role
    Properties:
      AssumeRolePolicyDocument:
        Version: "2012-10-17"
        Statement:
          - Effect: Allow
            Principal:
              Service: lambda.amazonaws.com
            Action: sts:AssumeRole
      ManagedPolicyArns:
        - arn:aws:iam::aws:policy/service-role/AWSLambdaBasicExecutionRole
		
# IAM Policy to access Parameter Store
ParameterStoreAccessPolicy:
    Type: AWS::IAM::RolePolicy
    Properties:
      RoleName: !Ref LambdaExecutionRole
      PolicyName: ParameterStoreAccess
      PolicyDocument:
        Version: "2012-10-17"
        Statement:
          - Effect: Allow
            Action:
              - ssm:GetParameter
            Resource: !Sub arn:aws:ssm:${AWS::Region}:${AWS::AccountId}:parameter${ParameterStoreParamName}

Creating the CloudFormation Lambda Hook

At this point, you only need to author a proper CloudFormation Lambda Hook. The Hook requires:

  • To be activated during the CREATE and UPDATE CloudFormation operations,
  • To consider only AWS::Lambda::Function CloudFormation resources
  • To act during Pre Provisioning of CloudFormation templates
  • To target Stack and Resource Operations
  • Target the already defined Lambda Validation function

Here’s the definition in the CloudFormation template:

# Lambda Hook
ValidationHook:
    Type: AWS::CloudFormation::LambdaHook
    Properties:
      Alias: Private::Lambda::LambdaResourcesComplianceValidationHook
      LambdaFunction: !GetAtt ValidationFunction.Arn
      ExecutionRole: !GetAtt HookExecutionRole.Arn
      FailureMode: FAIL
      HookStatus: ENABLED
      TargetFilters:
        Actions:
          - CREATE
          - UPDATE
        InvocationPoints:
          - PRE_PROVISION
        TargetNames:
          - AWS::Lambda::Function
      TargetOperations:
        - RESOURCE
        - STACK

Please note that the above template contains a reference to an IAM Role because the Hook requires proper permissions to call the target (Lambda Function). Here’s the IAM Role definition:

# Hook Execution Role
HookExecutionRole:
    Type: AWS::IAM::Role
    Properties:
      AssumeRolePolicyDocument:
        Version: "2012-10-17"
        Statement:
          - Effect: Allow
            Principal:
              Service: hooks.cloudformation.amazonaws.com
            Action: sts:AssumeRole

# IAM Policy for Lambda Invocation
LambdaInvokePolicy:
    Type: AWS::IAM::RolePolicy
    Properties:
      RoleName: !Ref HookExecutionRole
      PolicyName: LambdaInvokePolicy
      PolicyDocument:
        Version: "2012-10-17"
        Statement:
          - Effect: Allow
            Action:
              - lambda:InvokeFunction
            Resource: !GetAtt ValidationFunction.Arn

Configuring the compliant runtimes – Using Systems Manager Parameter Store

AWS Systems Manager Parameter Store is a secure, hierarchical storage service for configuration data management and secrets management, allowing users to store and retrieve data such as configurations, database strings etc. as parameter values.

In this specific example, we’ll leverage Parameter Store to store our permitted Lambda runtimes configuration. This configuration value is a StringList parameter, containing a comma-separated list of permitted runtimes. Here’s the fragment of the CloudFormation template that defines the Parameter:

# Parameter Store Parameter
ConfigParameter:
    Type: AWS::SSM::Parameter
    Properties:
      Name: !Ref ParameterStoreParamName
      Type: StringList
      Value: !Ref ParameterStoreDefaultValue
      Description: "Configuration for Lambda Hook"

Please note the usage of CloudFormation parameters for the ‘Name’ and ‘Value’ properties, allowing for dynamic input when deploying the CloudFormation template.

Deploying the Solution

To deploy the solution you can leverage the script deploy.sh in the root folder of the repository. This script will perform the following actions:

  • Compile and build the Validation Lambda Function
  • Create an Amazon S3 Bucket to store the CloudFormation Template
  • Upload the CloudFormation template and Lambda code to the S3 Bucket
  • Deploy the CloudFormation template

Testing the Lambda Hook

To test the CloudFormation Lambda Hook, deploy a simple testing CloudFormation template containing a Hello World Lambda function. First, test the Lambda configured with a permitted Lambda runtime, then modify the template to configure the Lambda with a non-compliant runtime.

Here’s the initial definition of the testing CloudFormation Template:

# Lambda Function
HelloWorldFunction:
    Type: AWS::Lambda::Function
    Properties:
      FunctionName: hello-world-function
      Runtime: nodejs22.x
      Handler: index.handler
      Role: !GetAtt LambdaExecutionRole.Arn
      Code:
        ZipFile: |
          exports.handler = async (event, context) => {
              console.log('Hello World!');
              const response = {
                  statusCode: 200,
                  body: JSON.stringify('Hello World!')
              };
              return response;
          };
      Timeout: 30
      MemorySize: 128

Please note that the Runtime value is nodejs22.x, which is currently in the list of permitted runtimes. The expectation is that the deployment of this function will succeed.

Deploy this template via the AWS CLI:

aws cloudformation deploy \
--template-file ./lambda_template.yml \
--capabilities CAPABILITY_IAM \
--stack-name lambda-sample

Check the CloudFormation Console:

CloudFormation Console showing successful Stack deployment

Figure 2: CloudFormation Console showing successful Stack deployment

As expected, the deployment was successful. You can also see that the CloudFormation Lambda Hook has been invoked by taking a look at the CloudWatch Logs:

Validation Lambda Function Logs with successful validation

Figure 3: Validation Lambda Function Logs with successful validation

Now modify the original sample Template in order to set a Lambda Runtime which is not inside the list of permitted runtimes:

# Lambda Function
HelloWorldFunction:
    Type: AWS::Lambda::Function
    Properties:
      FunctionName: hello-world-function
      Runtime: nodejs18.x
      Handler: index.handler
      Role: !GetAtt LambdaExecutionRole.Arn
      Code:
        ZipFile: |
          exports.handler = async (event, context) => {
              console.log('Hello World!');
              const response = {
                  statusCode: 200,
                  body: JSON.stringify('Hello World!')
              };
              return response;
          };
      Timeout: 30
      MemorySize: 128

Deploy this template via AWS CLI with the same command used before and check the CloudFormation Console:

CloudFormation Console showing failed Stack deployment due to Hook intervention

Figure 4: CloudFormation Console showing failed Stack deployment due to Hook intervention

As expected, the deployment was not successful. The CloudFormation Lambda Hook has been invoked, and since the Lambda Runtime was not present in the permitted runtimes list, the deployment failed.

You can also see that the hook failed In the CloudWatch Logs:

Validation Lambda Function Logs with validation error

Figure 5: Validation Lambda Function Logs with validation error

Cleaning up

To clean up the resources related to the sample, you can run the script cleanup_sample.sh inside the sample folder. This script will delete the sample’s CloudFormation Template through the AWS CLI.

To cleanup the resources related to the solution described above and based on AWS CloudFormation Lambda Hook, you can leverage the script cleanup.sh in the root folder of the repository. This script will perform the following actions:

  • Delete the CloudFormation Stack
  • Empty the S3 Bucket used for the deployment of the Stack
  • Delete the S3 Bucket

Conclusion

In this post, you explored the implementation of CloudFormation Hooks to enforce runtime compliance in Lambda functions across your AWS infrastructure. By leveraging the Lambda hook’s capabilities, you learned how to create a preventative control that validates Lambda runtime configurations before deployment.

By activating the Lambda hook and implementing a custom Lambda function validator, you established an automated mechanism to ensure that only compliant runtimes are used within your organization’s Lambda functions during CloudFormation stack creation and updates. The solution’s integration with common development tools like AWS CLI, AWS SAM, CI/CD pipelines, and AWS CDK makes it straightforward to implement these controls within existing workflows, eliminating the need for manual runtime checks or post-deployment remediation.

The validation approach demonstrated in this post extends beyond Lambda runtimes and can be adapted to different AWS Resources supported by CloudFormation, allowing you to enforce policies on different infrastructure components offered by AWS.

About the author

Matteo Luigi Restelli

Matteo Luigi Restelli is an AWS Sr. Partner Solutions Architect. He mainly focuses on Italian Consulting AWS Partners and is also specialized in Infrastructure as Code, Cloud Native App Development and DevOps. Outside of work, he enjoys swimming, rock & roll music and learning something new everyday especially in Computer Science space.

Stella Hie

Stella Hie is a Sr. Product Manager Technical for AWS Infrastructure as Code. She focuses on proactive control and governance space, working on delivering the best experience for customers to use AWS solutions safely. Outside of work, she enjoys hiking, playing piano, and watching live shows.

Enhancing cloud security in AI/ML: The little pickle story

Post Syndicated from Nur Gucu original https://aws.amazon.com/blogs/security/enhancing-cloud-security-in-ai-ml-the-little-pickle-story/

As AI and machine learning (AI/ML) become increasingly accessible through cloud service providers (CSPs) such as Amazon Web Services (AWS), new security issues can arise that customers need to address. AWS provides a variety of services for AI/ML use cases, and developers often interact with these services through different programming languages. In this blog post, we focus on Python and its pickle module, which supports a process called pickling to serialize and deserialize object structures. This functionality simplifies data management and the sharing of complex data across distributed systems. However, because of potential security issues, it’s important to use pickling with care (see the warning note in pickle — Python object serialization). In this post, we’re going to show you ways to build secure AI/ML workloads that use this powerful Python module, ways to detect that it’s in use that you might not know about, and when it might be getting abused, and finally highlight alternative approaches that can help you avoid these issues.

Quick tips

Understanding insecure pickle serialization and deserialization in Python

Effective data management is crucial in Python programming, and many developers turn to the pickle module for serialization. However, issues can arise when deserializing data from untrusted sources. The Python bytestream that pickling uses, is proprietary to Python. Until it’s unpickled, the data in the bytestream can’t be thoroughly evaluated. This is where security controls and validation become critical. Without proper validation, there’s a risk that an unauthorized user could inject unexpected code, potentially leading to arbitrary code execution, data tampering, or even unintended access to a system. In the context of AI model loading, secure deserialization is particularly important—it helps prevent outside parties from modifying model behavior, injecting backdoors, or causing inadvertent disclosure of sensitive data.

Throughout this post, we will refer to pickle serialization and deserialization collectively as pickling. Similar issues can be present in other languages (for example, Java and PHP) when untrusted data is used to recreate objects or data structures, resulting in potential security issues such as arbitrary code execution, data corruption, and unauthorized access.

Static code analysis compared to dynamic testing for detecting pickling

Security code reviews, including static code analysis, offer valuable early detection and thorough coverage of pickling-related issues. By examining source code (including third-party libraries and custom code) before deployment, teams can minimize security risks in a cost-effective way. Tools that provide static analysis can automatically flag unsafe pickling patterns, giving developers actionable insights to address issues promptly. Regular code reviews also help developers improve secure coding skills over time.

While static code analysis provides a comprehensive white-box approach, dynamic testing can uncover context-specific issues that only appear during runtime. Both methods are important. In this post, we focus primarily on the role of static code analysis in identifying unsafe pickling.

Tools like Amazon CodeGuru and Semgrep are effective at detecting security issues early. For open source projects, Semgrep is a great option to maintain consistent security checks.

The risks of insecure pickling in AI/ML

Pickling issues in AI/ML contexts can be especially concerning.

  • Invalidated object loading: AI/ML models are often serialized for future use. Loading these models from untrusted sources without validation can result in arbitrary code execution. Libraries such as pickle, joblib, and some yaml configurations allow serialization but must be handled securely.
    • For example: If a web application stores user input using pickle and unpickles it later with no validation, an unauthorized user could craft a harmful payload that executes arbitrary code on the server.
  • Data integrity: The integrity of pickled data is critical. Unexpectedly crafted data could corrupt models, resulting in incorrect predictions or behaviors, which is especially concerning in sensitive domains such as finance, healthcare, and autonomous systems.
    • For example: A team updates its AI model architecture or preprocessing steps but forgets to retrain and save the updated model. Loading the old pickled model under new code might trigger errors or unpredictable outcomes.
  • Exposure of sensitive information: Pickling often includes all attributes of an object, potentially exposing sensitive data such as credentials or secrets.
    • For example: An ML model might contain database credentials within its serialized state. If shared or stored without precautions, an unauthorized user who unpickles the file might gain unintended access to these credentials.
  • Insufficient data protection: When sent across networks or stored without encryption, pickled data can be intercepted, leading to inadvertent disclosure of sensitive information.
    • For example: In a healthcare environment, a pickled AI model containing patient data could be transmitted over an unsecured network, enabling an outside party to intercept and read sensitive information.
  • Performance overhead: Pickling can be slower than other serialization formats (such as, JSON or Protocol Buffers), which can affect ML and large language model (LLM) applications when inference speed is critical.
    • For example: In a real-time natural language processing (NLP) application using an LLM, heavy pickling or unpickling operations might reduce responsiveness and degrade the user experience.

Detecting unsafe unpickling with static code analysis tools

Static code analysis (SCA) is a valuable practice for applications dealing with pickled data, because it helps detect insecure pickling before deployment. By integrating SCA tools into the development workflow, teams can spot questionable deserialization patterns as soon as code is committed. This proactive approach reduces the risk of events involving unexpected code execution or unintended access due to unsafe object loading.

For instance, in a financial services application where objects are routinely pickled, a SCA tool can scan new commits to detect unvalidated unpickling. If identified, the development team can quickly address the issue, protecting both the integrity of the application and sensitive financial data.

Patterns in the source code

There are various ways to load a pickle object in Python. In this context, methods for detection can be tailored for secure coding habits and needed package dependencies. Many Python libraries include a function to load pickle objects. An effective approach can be to catalog all Python libraries used in the project, then create custom rules in your static code analysis tool to detect unsafe pickling or unpickling within those libraries.

CodeGuru and other static analysis tools continue to evolve their capability to detect unsafe pickling patterns. Organizations can use these tools and create custom rules to identify potential security issues in AI/ML pipelines.

Let’s define the steps for creating a safe process for addressing pickling issues:

  1. Generate a list of all the Python libraries that are used in your repository or environment.
  2. Check the static code analysis tool in your pipeline for current rules and the ability to add custom rules. If the tool is capable of discovering all the libraries used in your project, you can rely on it. However, if it’s not able to discover all the libraries used in your project, you should consider adding user-provided custom rules in your static code analysis tool.
  3. Most of the issues can be identified with well-designed, context-driven patterns in the static code analysis tool. For addressing the pickling issues, you need to identify pickling and unpickling functions.
  4. Implement and test the custom rules to verify full coverage of pickling and unpickling risks. Let’s identify patterns for a few libraries:
    • NumPy can efficiently pickle and unpickle arrays; useful for scientific computing workflows requiring serialized arrays. To catch potential unsafe pickle usage in NumPy, custom rules could target patterns like:
      import numpy as np
      data = np.load('data.npy', allow_pickle=True)

    • npyfile is a utility for loading NumPy arrays from pickled files. You can add the following patterns to your custom rules to discover potentially unsafe pickle object usage.
      import npyfile
      data = npyfile.load('example.pkl')

    • pandas can pickle and unpickle DataFrames using pickle, allowing for efficient storage and retrieval of tabular data. You can add the following patterns to your custom rules to discover potentially unsafe pickle object usage.
      import pandas as pd
      df = pd.read_pickle('dataframe.pkl')

    • joblib is often used for pickling and unpickling Python objects that involve large data, especially NumPy arrays, more efficiently than standard pickle. You can add the following patterns to your custom rules to discover potentially unsafe pickle object usage.
      from joblib import load
      data = load('large_data.pkl')

    • Scikit-learn provides joblib for pickling and unpickling objects and is particularly useful for models. You can add the following patterns to your custom rules to discover potentially unsafe pickle object usage.
      from sklearn.externals import joblib
      data = joblib.load('example.pkl')

    • PyTorch provides utilities for loading pickled objects that are especially useful for ML models and tensors. You can add the following patterns to your custom rule format to discover potentially unsafe pickle object usage.
      import torch
      data = torch.load('example.pkl')

By searching for these functions and parameters in code, you can set up targeted rules that highlight potential issues with pickling.

Effective mitigation

Addressing pickling issues requires not only detection, but also clear guidance on remediation. Consider recommending more secure formats or validations where possible as follows:

  • PyTorch
    • Use Safetensors to store tensors. If pickling remains necessary, add integrity checks (for example, hashing) for serialized data.
  • pandas
    • Verify data sources and integrity when using pd.read_pickle. Encourage safer alternatives (for example, CSV, HDF5, or Parquet) to help avoid pickling risks.
  • scikit-learn (via joblib)
    • Consider Skops for safer persistence. If switching formats isn’t feasible, implement strict validation checks before loading.
  • General advice
    • Identify safer libraries or methods whenever possible.
    • Switch to formats such as CSV or JSON for data, unless object-specific serialization is absolutely required.
    • Perform source and integrity checks before loading pickle files—even those considered trusted.

Example

The following is an example implementation that shows safe pickle implementation as a representation of the preceding information.

import io
import base64
import pickle
import boto3
import numpy as np
from cryptography.fernet import Fernet

###############################################################################
# 1) RESTRICTED UNPICKLER
###############################################################################
#
# By default, pickle can execute arbitrary code when loading. Here we implement
# a custom Unpickler that only allows certain safe modules/classes. Adjust this
# to your application's requirements.
#

class RestrictedUnpickler(pickle.Unpickler):
    """
    Restricts unpickling to only the modules/classes we explicitly allow.
    """
    allowed_modules = {
        "numpy": set(["ndarray", "dtype"]),
        "builtins": set(["tuple", "list", "dict", "set", "frozenset", "int", "float", "bool", "str"])
    }

    def find_class(self, module, name):
        if module in self.allowed_modules:
            if name in self.allowed_modules[module]:
                return super().find_class(module, name)
        # If not allowed, raise an error to prevent arbitrary code execution.
        raise pickle.UnpicklingError(f"Global '{module}.{name}' is forbidden")

def restricted_loads(data: bytes):
    """Helper function to load pickle data using the RestrictedUnpickler."""
    return RestrictedUnpickler(io.BytesIO(data)).load()

###############################################################################
# 2) AWS KMS & ENCRYPTION HELPERS
###############################################################################

def generate_data_key(kms_key_id: str, region: str = "us-east-1"):
    """
    Generates a fresh data key using AWS KMS. 
    Returns (plaintext_key, encrypted_data_key).
    """
    kms_client = boto3.client("kms", region_name=region)
    response = kms_client.generate_data_key(KeyId=kms_key_id, KeySpec='AES_256')
    
    # Plaintext data key (use to encrypt the pickle data locally)
    plaintext_key = response["Plaintext"]
    # Encrypted data key (store along with your ciphertext)
    encrypted_data_key = response["CiphertextBlob"]
    return plaintext_key, encrypted_data_key

def decrypt_data_key(encrypted_data_key: bytes, region: str = "us-east-1"):
    """
    Decrypts the encrypted data key via AWS KMS, returning the plaintext key.
    """
    kms_client = boto3.client("kms", region_name=region)
    response = kms_client.decrypt(CiphertextBlob=encrypted_data_key)
    return response["Plaintext"]

def build_fernet_key(plaintext_key: bytes) -> Fernet:
    """
    Construct a Fernet instance from a 32-byte data key.
    Fernet requires a 32-byte key *encoded* in URL-safe base64.
    """
    if len(plaintext_key) < 32:
        raise ValueError("Data key is smaller than 32 bytes; cannot build a Fernet key.")
    fernet_key = base64.urlsafe_b64encode(plaintext_key[:32])
    return Fernet(fernet_key)

###############################################################################
# 3) MAIN LOGIC
###############################################################################

def upload_pickled_data_s3(
    numpy_obj: np.ndarray,
    bucket_name: str,
    s3_key: str,
    kms_key_id: str,
    region: str = "us-east-1"
):
    """
    Pickle a numpy object, encrypt it locally, and upload the ciphertext + 
    encrypted data key to S3.
    """
    # 1. Generate data key from KMS
    plaintext_key, encrypted_data_key = generate_data_key(kms_key_id, region)
    
    # 2. Build Fernet from plaintext data key
    fernet = build_fernet_key(plaintext_key)
    
    # 3. Serialize the numpy object with pickle
    pickled_data = pickle.dumps(numpy_obj, protocol=pickle.HIGHEST_PROTOCOL)
    
    # 4. Encrypt the pickled data
    encrypted_data = fernet.encrypt(pickled_data)
    
    # 5. Upload to S3 along with the encrypted data key (in metadata)
    s3_client = boto3.client("s3", region_name=region)
    s3_client.put_object(
        Bucket=bucket_name,
        Key=s3_key,
        Body=encrypted_data,
        Metadata={
            "encrypted_data_key": base64.b64encode(encrypted_data_key).decode("utf-8")
        }
    )
    print(f"Encrypted pickle uploaded to s3://{bucket_name}/{s3_key}")

def download_and_unpickle_data_s3(
    bucket_name: str,
    s3_key: str,
    region: str = "us-east-1"
) -> np.ndarray:
    """
    Download the ciphertext and the encrypted data key from S3. Decrypt the data 
    key with KMS, use it to decrypt the pickled data, then load with a restricted 
    unpickler for safety.
    """
    s3_client = boto3.client("s3", region_name=region)
    
    # 1. Get object from S3
    response = s3_client.get_object(Bucket=bucket_name, Key=s3_key)
    
    # 2. Extract the encrypted data key from metadata
    metadata = response["Metadata"]
    encrypted_data_key_b64 = metadata.get("encrypted_data_key")
    if not encrypted_data_key_b64:
        raise ValueError("Missing encrypted_data_key in S3 object metadata.")
    
    encrypted_data_key = base64.b64decode(encrypted_data_key_b64)
    
    # 3. Decrypt data key via KMS
    plaintext_key = decrypt_data_key(encrypted_data_key, region)
    fernet = build_fernet_key(plaintext_key)
    
    # 4. Decrypt the pickled data
    encrypted_data = response["Body"].read()
    decrypted_pickled_data = fernet.decrypt(encrypted_data)
    
    # 5. Use restricted unpickler to load the numpy object
    numpy_obj = restricted_loads(decrypted_pickled_data)
    
    return numpy_obj

###############################################################################
# DEMO USAGE
###############################################################################

if __name__ == "__main__":
    # --- Replace with your actual values ---
    KMS_KEY_ID = "arn:aws:kms:us-east-1:123456789012:key/your-kms-key-id"
    BUCKET_NAME = "your-secure-bucket"
    S3_OBJECT_KEY = "encrypted_npy_demo.bin"
    AWS_REGION = "us-east-1"  # or region of your choice
    
    # Example numpy array
    original_array = np.random.rand(2, 3)
    print("Original Array:")
    print(original_array)
    
    # Upload (pickle + encrypt) to S3
    upload_pickled_data_s3(
        numpy_obj=original_array,
        bucket_name=BUCKET_NAME,
        s3_key=S3_OBJECT_KEY,
        kms_key_id=KMS_KEY_ID,
        region=AWS_REGION
    )
    
    # Download (decrypt + unpickle) from S3
    retrieved_array = download_and_unpickle_data_s3(
        bucket_name=BUCKET_NAME,
        s3_key=S3_OBJECT_KEY,
        region=AWS_REGION
    )
    
    print("\nRetrieved Array:")
    print(retrieved_array)
    
    # Verify integrity
    assert np.allclose(original_array, retrieved_array), "Arrays do not match!"
    print("\nSuccess! The retrieved array matches the original array.")

Conclusion

With the rapid expansion of cloud technologies, integrating static code analysis into your AI/ML development process is increasingly important. While pickling offers a powerful way to serialize objects for AI/ML and LLM applications, you can mitigate potential risks by applying manual secure code reviews, setting up automated SCA with custom rules, and following best practices such as using alternative serialization methods or verifying data integrity.

When working with ML models on AWS, see the AWS Well-Architected Framework’s Machine Learning Lens for guidance on secure architecture and recommended practices. By combining these approaches, you can maintain a strong security posture and streamline the AI/ML development lifecycle.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
 

Nur Gucu
Nur Gucu

Nur is a Security Engineer at Amazon with 10 years of offensive security expertise, specializing in generative AI security, security architecture, and offensive testing. Nur has developed security products at startups and banks, and has created frameworks for emerging technologies. She brings practical experience to solve complex AI security challenges, and yet believes as many as six impossible things before breakfast.
Matt Schwartz
Matt Schwartz

Matt is an Amazon Principal Security Engineer specializing in generative AI security, risk management, and cloud computing expertise. His two-decade expertise enables organizations to implement advanced AI while maintaining strict security protocols. Matthew develops strategic frameworks that safeguard critical assets and ensure compliance in the evolving digital landscape, securing complex systems during transformations.

Effectively implementing resource controls policies in a multi-account environment

Post Syndicated from Tatyana Yatskevich original https://aws.amazon.com/blogs/security/effectively-implementing-resource-controls-policies-in-a-multi-account-environment/

Every organization strives to empower teams to drive innovation while safeguarding their data and systems from unintended access. For organizations that have thousands of Amazon Web Services (AWS) resources spread across multiple accounts, organization-wide permissions guardrails can help maintain secure and compliant configurations. For example, some AWS services support resource-based policies that can be used to grant identities permissions to perform actions on the resources they’re attached to. With the management of resource-based policies frequently delegated to application owners, central security teams use permissions guardrails to help ensure that possible misconfigurations don’t lead to unintended access to these resources.

In this post, we discuss how you can use resource control policies (RCPs) to centrally restrict access to resources. We demonstrate how RCPs can help improve your security posture while allowing even more freedom to developers in managing their resources, thus reducing friction between central security and application teams. Using a sample use case, we uncover key considerations for designing and effectively implementing RCPs in your organization at scale.

If you’re new to RCPs, we recommend starting with Introducing resource control policies (RCPs), a new type of authorization policy in AWS Organizations, which provides an introduction to RCPs and their role in your security strategy.

RCP implementation journey

RCPs are a type of authorization policy in AWS Organizations. RCPs work alongside service control policies (SCPs) to help establish permissions guardrails across multiple accounts in your organization. To understand their differences and use cases, see General use cases for SCPs and RCPs and Enforcing enterprise-wide preventive controls with AWS Organizations.

We recommend implementing permissions guardrails, including RCPs, using the following iterative process, which consists of five phases (as shown in Figure 1).

  1. Examine your security control objectives
  2. Design permissions guardrails
  3. Anticipate potential impacts
  4. Implement permissions guardrails
  5. Monitor permissions guardrails

Figure 1: Permissions guardrails implementation journey

Figure 1: Permissions guardrails implementation journey

This phased approach helps ensure an effective integration of RCPs into your security strategy, improving your security posture while helping to maintain business continuity. Let’s explore each phase of RCP implementation in detail and outline key considerations for an effective implementation strategy.

Phase 1: Examine your security control objectives

The first step in implementing RCPs is identifying areas where RCPs can help improve your security posture or optimize the implementation of controls for your organization’s specific security control objectives.

Your control objectives can be influenced by a variety of factors such as compliance and regulatory requirements, legal and contractual obligations, types of workloads, data classification, and your organization’s threat model. After your control objectives are well-defined and prioritized, identify those that can be achieved using RCPs.

Like SCPs, RCPs are designed to establish coarse-grained access controls, security invariants that rarely change and serve as always-on boundaries across a wide range of AWS resources in your accounts. RCPs aren’t for managing fine-grained access controls. You will keep using policies such as resource-based and identity-based policies to apply least-privilege permissions.

More specifically, the following are key control objectives that you can achieve using RCPs:

  • Establish a data perimeter around your AWS resources. For example, you can use RCPs to help ensure that only trusted identities can access your AWS resources.
  • Mitigate the cross-service confused deputy risk. You can use RCPs to help ensure that your AWS resources are accessed by AWS services only on behalf of your organization.
  • Apply consistent access controls to your AWS resources regardless of the identities accessing them. For example, you can use RCPs to help ensure your Amazon Simple Storage Service (Amazon S3) buckets require TLS v1.2 or higher for in-transit encryption.

For additional use cases and types of controls that can be implemented using RCPs, you can explore the resource control policy examples repository. In this post, we demonstrate how to help ensure that only trusted identities can access your AWS Identity and Access Management (IAM) roles.

Let’s begin with the scenario illustrated in Figure 2. Your company’s central cloud team manages your corporate AWS Organizations organization, which consists of two corporate AWS accounts. An IAM principal in Account A should be able to assume an IAM role in Account B to perform day-to-day operations. To align to the broader control objective of Only trusted identities can access my resources, the central security team wants to make sure that the IAM role in Account B (my resource) can only be assumed by IAM principals that belong to their organization (trusted identities).

Figure 2: Simple scenario depicting a trusted identity accessing an IAM role

Figure 2: Simple scenario depicting a trusted identity accessing an IAM role

One way of achieving this control objective is to follow the principle of least-privilege and make sure that the role trust policy, the resource-based policy attached to the IAM role, only allows access to identities that require that access. The following is an example trust policy that grants permissions to Role A in Account A to assume Role B in Account B.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "GrantCrossAccountAccess",
      "Effect": "Allow",
      "Principal": {
        "AWS": "arn:aws:iam::<my-account-a-id>:role/RoleA"
      },
      "Action": "sts:AssumeRole"
    }
  ]
}

In organizations that have only a few accounts, central teams typically manage these policies. While this centralized governance model helps ensure that trust policies applied to roles are always restricted to trusted identities, it can also impede the productivity of application teams when operating at a greater scale.

Assume that your company has started growing its cloud footprint so much that your central security team now must achieve the same control objective with hundreds of IAM roles that are spread across multiple AWS accounts, as demonstrated in Figure 3.

Figure 3: Restricting access by managing individual IAM role trust policies

Figure 3: Restricting access by managing individual IAM role trust policies

At this scale, we see organizations delegating permissions management to application teams to better support the growth of their business and empower developers to innovate faster. While central security teams no longer have full control over the permissions granted to resources across AWS accounts, they must make sure that access is aligned with their organization’s security standard. For example, they might want to make sure that the GrantCrossAccountAccess statement that is now managed by developers doesn’t inadvertently grant access to an account that doesn’t belong to their organization. Previously, central security teams typically achieved this by developing automated mechanisms to insert a standard statement into all trust policies. This statement helped ensure that access remained bounded to their organization, even when developers configured broad access permissions for their roles. The following is an example trust policy where a developer granted permissions to an external account through the GrantCrossAccountAccess statement. However, because of the RestrictAccessToMyOrg statement added to the policy by the central security team, the external account will be unable to use these permissions.

{
  "Version": "2012-10-17",
  "Statement": [
   	{
      "Sid": "GrantCrossAccountAccess",
      "Effect": "Allow",
      "Principal": {
        "AWS":"arn:aws:iam::<noncorp-account-id>:role/<role-name>"
      },
      "Action": "sts:AssumeRole"
    },
    {
      "Sid": "RestrictAccessToMyOrg",
      "Effect": "Deny",
      "Principal": {
        "AWS": "*"
      },
      "Action": "sts:AssumeRole",
      "Condition": {
        "StringNotEqualsIfExists": {
          "aws:PrincipalOrgID": "<my-org-id>"
        },
        "BoolIfExists": {
          "aws:PrincipalIsAWSService": "false"
        }
      }
    }
  ]
}

The RestrictAccessToMyOrg statement uses the aws:PrincipalOrgID and aws:PrincipalIsAWSService condition keys to restrict access to principals within your organization or to AWS service principals. The BoolIfExists operator with the aws:PrincipalIsAWSService condition key is required if the roles you’re applying a control to are service roles that are used by AWS services to perform operations on your behalf. When an AWS service assumes a service role, it uses its AWS service principal, an identity that is owned by AWS and that does not belong to your organization.

The central security teams could, for example, use AWS Config rules to detect misconfigurations and then use AWS Config remediation to automatically add the RestrictAccessToMyOrg statement to the IAM roles’ trust policies when new IAM roles are created or their trust policies are changed. Even though the addition of the RestrictAccessToMyOrg statement to trust policies can be automated, RCPs can greatly simplify enforcement of such coarse-grained controls in a multi-account environment.

Phase 2: Design permissions guardrails

Central security teams can implement permissions guardrails by creating an RCP that centrally blocks external access to IAM roles. The RCP that you will implement contains similar restrictions to the RestrictAccessToMyOrg statement that you used in the IAM trust policy.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "RestrictAccessToMyOrg",
      "Effect": "Deny",
      "Principal": "*",
      "Action": "sts:AssumeRole",
      "Resource": "*",
      "Condition": {
        "StringNotEqualsIfExists": {
          "aws:PrincipalOrgID": "<my-org-id>"
        },
        "BoolIfExists": {
          "aws:PrincipalIsAWSService": "false"
        }
      }
    }
  ]
}

Like SCPs, you attach the RCP to an account, organizational unit (OU), or the root of your organization. After being attached, the RCP automatically applies to applicable resources—in this case, IAM roles—within the scope of that AWS Organizations entity. This centralized approach alleviates the need to modify hundreds of trust policies across multiple accounts, lowering the operational overhead for central security teams and helping ensure consistent access controls are applied at scale. RCPs also help you achieve separation of duties with developers still managing their least-privilege permissions in trust policies and administrators applying coarse-grained access controls in RCPs. If developers make configuration mistakes while managing permissions for their applications, the preventative access controls implemented using RCPs will help ensure that they stay within your organization’s access control guidelines. See How AWS enforcement code logic evaluates requests to allow or deny access to understand how different policy types impact the authorization process.

If you’re transitioning existing controls from resource-based policies to RCPs, use the opportunity to reassess the control design based on your current control objectives and the additional benefits offered by RCPs. For example, your previous controls might have been limited to specific resource types, such as IAM roles in this use case, or to particular accounts, such as those storing the most sensitive data. RCPs enable you to extend controls to additional resources across your entire organization, reducing operational overhead through centralized management of permissions guardrails.

If you need to apply a control on resources not yet covered by RCPs, you can implement or retain your custom automation for enforcing controls with resource-based policies. See the List of AWS services that support RCPs and Resources and entities not restricted by RCPs and plan for additional controls if applicable.

While designing your RCPs, consider the following guidelines.

Design for operational excellence

A key foundation for effectively implementing and operating permissions guardrails like RCPs is organizing your AWS environment using multiple accounts. Account boundaries and strategic placement of workloads across them allow you to apply tailored access controls that align with data sensitivity and specific access requirements. Grouping accounts into OUs within AWS Organizations enables more effective access control, even in scenarios where cross-account access is required. Figure 4 illustrates an example organization structure, demonstrating how RCPs can be applied at various levels of the organizational hierarchy to adhere to the security requirements of different workloads.

Figure 4: A sample organization with RCPs applied at various levels

Figure 4: A sample organization with RCPs applied at various levels

When operating at scale, consider delegating policy management to a central security account in your organization. With AWS Organizations resource-based delegation, central teams don’t need access to the management account for any SCP or RCP related changes or troubleshooting.

Review Achieving operational excellence with design considerations for AWS Organizations SCPs, which focuses on SCPs but also covers foundational principles for designing and implementing permissions guardrails at scale. These considerations also apply to RCPs for enabling operational excellence. Additionally, see AWS Organizations quotas and RCP evaluation for the RCP-related quotas and unique implementation details.

Define your governance

Establishing clear governance helps you define how to implement and continuously manage RCPs within your organization. This includes the operating model, change management processes, and exceptions handling procedures. RCPs provide authorization controls similar to SCPs and therefore should integrate with your existing governance framework rather than requiring separate oversight. For example, if your change management process requires two-person approval for SCP changes, you should consider applying the same approval process for RCP implementation. You should also adopt the same mechanisms you currently use to prevent unauthorized changes or detect drifts in your policies.

Plan for exceptions

There might be scenarios where you have a few resources that should be accessible publicly or by identities that don’t belong to your organization. If you’re organizing your resources across multiple accounts and OUs based on their compliance requirements or a common set of controls, then you most likely have such resources in a dedicated set of accounts or OUs, such as the Public Data OU in Figure 4. These accounts or OUs can have applicable policies that account for their unique access requirements.

Another option to accommodate these scenarios is to use the aws:ResourceAccount or aws:ResourceOrgPaths condition key to exclude certain accounts from the control. For example, the following policy will deny access to identities outside your organization from assuming IAM roles unless the identity is an AWS service principal or the role that is being accessed belongs to Account A.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "RestrictAccessToMyOrgExceptMyAccounts",
      "Effect": "Deny",
      "Principal": "*",
      "Action": "sts:AssumeRole",
      "Resource": "*",
      "Condition": {
        "StringNotEqualsIfExists": {
          "aws:PrincipalOrgID": "<my-org-id>",
          "aws:ResourceAccount": "<my-account-a-id>"
        },
        "BoolIfExists": {
          "aws:PrincipalIsAWSService": "false"
        }
      }
    }
  ]
}

There also might be situations where your company’s trusted partners or acquisitions need to be granted an exception for access to a subset of your company’s resources distributed across multiple accounts. For example, your company might integrate with Cloud Security Posture Management (CSPM) tools that assume roles in your accounts to assess your accounts’ security posture, as shown in Figure 5.

Figure 5: Representative view of granting exceptions to trusted partners

Figure 5: Representative view of granting exceptions to trusted partners

When implementing a control with an RCP that by default will apply to all resources of the entity it’s attached to, you can manage resource specific exceptions using the aws:ResourceTag condition key. In addition, use the aws:PrincipalAccount context key to conditionally grant exceptions based on the AWS account ID of the trusted partner.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "RestrictAccessToMyOrgExceptTaggedRoles",
            "Effect": "Deny",
            "Principal": "*",
            "Action": "sts:AssumeRole",
            "Resource": "*",
            "Condition": {
                "StringNotEqualsIfExists": {
                    "aws:PrincipalOrgID": "<my-org-id>",
                    "aws:ResourceTag/partner-access-exception": "trusted-partner"
                },
        	  	"BoolIfExists": {
					"aws:PrincipalIsAWSService": "false"
				}					
			}
        },
        {
            "Sid": "RestrictAccessForTaggedRoles",
            "Effect": "Deny",
            "Principal": "*",
            "Action": "sts:AssumeRole",
            "Resource": "*",
            "Condition": {
                "StringEquals": {
                    "aws:ResourceTag/partner-access-exception": "trusted-partner"
                },
                "StringNotEqualsIfExists": {
                    "aws:PrincipalAccount": "<trusted-partner-account-id>"
                }
            }
        }
    ]
}

Let’s examine the two statements in the preceding RCP:

  • RestrictAccessToMyOrgExceptTaggedRoles

    This statement helps ensure that your roles can only be assumed by identities that belong to your organization or by AWS service principals, unless a role is tagged with partner-access-exception set to trusted-partner.

  • RestrictAccessForTaggedRoles

    This statement further restricts access by helping ensure that the roles that have the partner-access-exception tag can only be assumed by identities that belong to your trusted partner account.

If you have a well-known, tightly scoped set of resources that need to be excluded, you can also use the IAM policy element, NotResource, to list the Amazon Resource Names (ARNs) of resources to exclude from the control.

When implementing tag-based exception processes, establishing strict controls over tag management is key. Unauthorized modifications of tags on resources, principals, or sessions could impact your security posture by enabling unintended access. You should implement controls to help prevent unauthorized tag manipulation. For example, the following SCP restricts the use of the partner-access-exception tag to the admin role so that unauthorized users cannot alter the control by attaching, detaching, or modifying the tag.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "RestrictAccessToExceptionTag",
      "Effect": "Deny",
      "Action": "*",
      "Resource": "*",
      "Condition": {
        "StringNotEqualsIfExists": {
          "aws:PrincipalArn": "<admin-role-arn>"
        },
        "ForAnyValue:StringEquals": {
          "aws:TagKeys": [
			"partner-access-exception"
		  ]
        }
      }
    }
  ]
}

You should also make sure that the partner-access-exception tag cannot be passed as a session tag when identities assume roles. See the sample RCP in the data perimeter policy examples repository.

Phase 3: Anticipate potential impacts

Before rolling out RCPs, you need to understand their potential impact on your organization. Introducing new policies or modifying existing ones without proper validation can disrupt your security-productivity balance. Be aware that overly restrictive policies might inadvertently impede legitimate data flows that are essential for achieving your business objectives.

Consider using AWS Identity and Access Management Access Analyzer to monitor effective permissions across resources in your organization. For our IAM role example, use an organization external access analyzer to identify IAM roles in your organization that are shared with external entities. This analysis will help you to create appropriate exceptions or lock down any overly permissive access.

Another effective method to assess impact is to review and analyze your account activity using AWS CloudTrail. For example, if you centralize all your CloudTrail logs in an S3 bucket, you can use Amazon Athena to query these logs. Specifically, look for STS API calls made against your IAM roles by identities outside your organization. Then, compare the results with your list of known trusted partners and those you have already accounted for in your RCPs. Based on this analysis, determine if you need to add the partner-access-exception tag to additional IAM roles and further refine the policy before enforcement. This is essential to ensure trusted partner integrations continue to function as expected when you enforce your RCPs. Furthermore, use this analysis to identify any illegitimate access patterns in your environment and plan for necessary remediations, further enhancing your security posture as part of RCP implementation.

For detailed guidance on how to perform an impact analysis in your environment, see Analyze your account activity to evaluate impact and refine controls, which describes the tools and options you need to be able to conduct the analysis.

Phase 4: Implement permissions guardrails

As you transition into the implementation phase, consider the following key factors to promote a smooth rollout while enhancing your security posture.

Deployment automation and integration

Use your existing deployment pipelines to implement RCPs, the same as you do for SCPs. This approach will minimize operational overhead while maintaining consistency in the deployment of your controls.

You can use the AWS CloudFormation AWS::Organizations::Policy resource type to deploy RCPs as infrastructure as code (IaC) using your continuous integration and continuous delivery (CI/CD) pipeline. If you’re using AWS Control Tower and the Customizations for AWS Control Tower solution (CfCT) for account management and want to deploy your custom RCPs, use rcp as the deploy_method in the CfCT manifest file. You can also take advantage of the AWS Control Tower provided RCP-based controls to streamline the implementation.

Progressive deployment in stages

As with SCPs, AWS strongly advises against attaching RCPs in production environments without thoroughly testing the impact that the policies have on resources in your accounts. Follow standard CI/CD processes and begin your RCP rollout in lower environments by attaching them to individual test accounts or OUs first. After you validate that the controls behave as excepted, gradually promote the RCPs to upper environments.

If your goal is to transition an existing control from resource-based policies to RCPs, keep your resource-based policies in place while conducting the progressive rollout. After you have completed rolling out your RCPs and confirmed that they operate as expected, you can consider deactivating the automation you used to apply the control using resource-based policies. This approach lets you deploy RCPs without impacting your existing security posture or disrupting business workflows.

Additionally, consider deploying RCPs to a subset of resources or accounts first to limit the scope of impact and provide an opportunity to test and refine your deployment and operational processes. You can follow your standard prioritization approach to define deployment waves, for example, start with resources or accounts that store sensitive data or pose the highest risk, based on your current operational practices and other controls that might be in place. For additional best practices, see OPS06-BP03 Employ safe deployment strategies in the AWS Well-Architected Framework: Operation Excellence Pillar whitepaper.

Phase 5: Monitor permissions guardrails

Finally, establish monitoring processes to help ensure that controls for preventing external access to your resources operate as expected. You can use the same tools you used for impact analysis. For example, you can use IAM Access Analyzer external access findings to understand the impact of your RCPs on resource permissions. This information will help you verify that your RCPs are crafted in accordance with your intent and plan remediation actions, if required. You can also set alerts for occurrences of unintended access patterns observed in your CloudTrail logs.

Furthermore, follow the phased approach outlined in this post to regularly review and update your controls to help ensure that they align with evolving business and security objectives. Consider factors such as organizational changes, changes in partner relationships, data criticality shifts, and opportunities for expanding your RCP coverage. This continuous improvement process helps maintain the effectiveness of your security controls while supporting business growth and transformation.

Conclusion

In this post, we discussed how to effectively implement coarse-grained access controls on AWS resources at scale using RCPs. You can use the phased implementation approach described here to achieve your security control objectives while minimizing the risk of disrupting your business workflows. You can apply the same approach to implement other preventative controls, such as SCPs, across your multi-account environment.

Remember that RCPs, like SCPs, provide a powerful mechanism for enforcing coarse-grained controls across multiple accounts in your organization. They don’t replace your least-privilege controls and should be part of a broader, multi-layered approach to data security that includes other well-architected security design principles.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
 

Tatyana Yatskevich
Tatyana Yatskevich

Tatyana is a Principal Solutions Architect in AWS Identity. She works with customers to help them build and operate in AWS in a secure and efficient manner.
Harsha W Sharma
Harsha W Sharma

Harsha is a Principal Solutions Architect with AWS in New York. He works with Global Financial Services customers to help them design and develop scalable, secure and resilient architectures on AWS.

Master architecture decision records (ADRs): Best practices for effective decision-making

Post Syndicated from Christoph Kappey original https://aws.amazon.com/blogs/architecture/master-architecture-decision-records-adrs-best-practices-for-effective-decision-making/

Architecture decision records (ADRs) help you document and communicate important process and architecture decisions in your engineering projects. Based on our experience implementing over 200 ADRs across multiple projects, we’ve developed best practices that can help you streamline your decision-making processes and improve team collaboration.

In this post, you’ll learn:

  • How to implement ADRs in your organization
  • Best practices based on more than 200 ADRs across multiple projects
  • Practical tips for streamlining architectural decision-making
  • Real-world examples from projects with 10 to more than 100 team members

Common challenges in architecture decision-making

Before implementing ADRs, your teams might face these common challenges:

  1. Team alignment – Development teams spend a huge part of their time (20 –30%, based on our project experience of the past 3 years) coordinating with other teams, which can slow down feature deployment and increase costs through repeated architecture refactoring
  2. Design flexibility – Finding the right balance between upfront design and evolving architecture when working with agile and DevOps approaches
  3. Nonfunctional requirements – Making trade-offs between security, maintainability, and scalability requirements
  4. Changing requirements – Adapting architectural decisions to evolving business goals while maintaining system integrity
  5. Knowledge transfer – Onboard new team members efficiently and make sure they follow the team’s current way of working

How to streamline the decision-making process

We base the recommendations in this post on our experience with several projects, working with teams with fewer than 10 team members as well as complex projects with 100 team members across 10 work streams. We embarked on ambitious projects with a green-field start as well as projects covering ongoing development of new features in production. Especially in teams with 100 people contributing to the code base, we faced the challenge of making sure that collaboration was seamless and decision-making consistent.

To address this challenge, we implemented an ADR mechanism, which served as our guiding light throughout the project’s lifecycle. After more than 3 years of following this approach, we’ve amassed a wealth of experience and best practices that we’re excited to share with the software development community. By capturing the context, alternatives considered, and the rationale behind each decision, ADRs foster transparency, knowledge-sharing, and accountability within teams. Our goal is to guide you through the process of writing effective ADRs with the following best practice recommendations:

  1. Keep ADR meetings short and focused – Effective ADR meetings should be concise and time-bound. Aim to keep them 30–45 minutes maximum. This focused approach keeps discussions on track and participants engaged throughout the process.
  2. Embrace the readout meeting style – Adopt the readout meeting style, where participants spend 10–15 minutes reading the ADR document. Encourage attendees to provide written comments on sections, paragraphs, or sentences that require clarification or where they have differing opinions. This approach promotes active engagement and fosters a bias for action and frugality.
  3. Maintain a cross-functional yet lean participant list – Invite representatives from each team that might be affected by the architectural decision but strive to keep the total number of participants below 10. This cross-functional representation provides diverse perspectives while maintaining a lean and efficient decision-making process, aligning with the principles of frugality and bias for action.
  4. Focus on a single decision – Keep ADRs concise by focusing on a single decision. Don’t hesitate to split up decisions if necessary. Concentrating on one decision at a time simplifies the decision-making process so that participants can thoroughly evaluate the impact during readout sessions. This approach aligns with the principles of ownership and customer obsession.
  5. Separate design from decision – Use a separate design document mechanism to explore alternative options thoroughly. Reference these design documents within the ADR, adhering to the principles of invention and simplification.
  6. Address comments and resolve feedback – Actively follow up on comments received during the ADR review process. Resolve all comments, either by incorporating changes or by discussing and reaching a consensus with the comment author. This practice demonstrates a commitment to delivering results and fostering a sense of ownership.
  7. Push for a timely decision – Avoid prolonged discussions and multiple readout meetings. Based on our experience, one to three ADR readouts should be sufficient. If more sessions are required, reevaluate the dependencies and consider reducing the number of invitees or reducing the scope of the ADR. Most of the decisions are two-way door decisions, meaning that they can be changed with little impact in the future. It’s always better to make a decision and try it fast instead of endlessly discussing it. This approach aligns with the AWS principles of working backwards, customer obsession, delivering results, and being right a lot.
  8. Embrace team collaboration – Approving an ADR is a team effort. The author must own the document and gather feedback from all affected teams before finalizing the decision. This practice encourages having backbone, disagreeing and committing, and fostering a collaborative environment.
  9. Maintain and follow the process – Keep ADRs up to date and follow the established process. If an ADR supersedes a previous one, document the change and link the new ADR in the superseded document. Insist on the highest standards by adhering to the defined processes—consider ADRs as a team law.
  10. Centralize ADR storage – Store ADRs in a central location accessible to all project members, regardless of their team affiliation. This practice promotes transparency and makes sure that architectural decisions are readily available to everyone involved.

Implementation tips and success measures

When implementing these practices, we recommend that you start small with a pilot team, create clear templates, and establish review cycles. Defining success measures such as the time to decision, team satisfaction, architecture rework reduction, or cross-team collaboration improvement help to evaluate your decision-making process

Conclusion

By implementing these best practices for ADRs, you’ll streamline your decision-making processes, foster collaboration, and make sure that architectural decisions are well-documented, communicated, and aligned with your organization’s principles and goals. Embrace these practices and witness the positive impact they have on the success of your software projects.

Read the AWS Prescriptive Guidance for an introduction into ADRs and an example ADR or the homepage of ADR GitHub organization.


About the Authors

AWS KMS CloudWatch metrics help you better track and understand how your KMS keys are being used

Post Syndicated from Norman Li original https://aws.amazon.com/blogs/security/aws-kms-cloudwatch-metrics-help-you-better-track-and-understand-how-your-kms-keys-are-being-used/

AWS Key Management Service (AWS KMS) is pleased to launch key-level filtering for AWS KMS API usage in Amazon CloudWatch metrics, providing enhanced visibility to help customers improve their operational efficiency and aid in security and compliance risk management.

AWS KMS currently publishes account-level AWS KMS API usage metrics to Amazon CloudWatch, enabling you to monitor and manage your API usage. However, if you’re using numerous KMS keys, pinpointing the ones with the highest request rate quota usage or significant API costs becomes challenging. For example, if you have more than 10 active KMS keys in your account, prior to this launch you would have needed to build a custom CloudTrail and Amazon Athena based solution to locate which specific keys are driving the majority of API usage and costs. With the new CloudWatch metrics, which are available under the AWS/KMS namespace in CloudWatch, you can track, understand, and set alerts on detailed API usage at the individual KMS key level without building a costly customized solution.

This blog post explores several use cases to help you better take advantage of these newly introduced CloudWatch metrics to manage your AWS KMS API usage and costs. The use cases cover viewing and understanding your API usage at the key level, and creating CloudWatch alerts to detect unintentional runaway usage.

Overview of new CloudWatch metrics for KMS keys

With CloudWatch metrics for KMS keys, you can now do the following:

  1. View the API usage for a specific KMS key, filtered by individual API operations (for example, Encrypt, Decrypt, or GenerateDataKey).
  2. See the aggregated usage across cryptographic operations for a given KMS key.
  3. Set up an alarm if a specific KMS key exceeds a specified threshold on a single API operation, or a set of API operations.

This streamlined approach allows you to quickly monitor, understand, and troubleshoot the API usage patterns of your KMS keys, without the overhead of the previous multi-step process. Let’s detail how these key-level API usage metrics can be used in two real-world examples.

Example 1: How to locate the KMS keys that consume the most API usage quota or contribute the most API charges

When you surpass your AWS KMS API request rate quotas, you can view your AWS KMS API utilization within the Service Quotas console. However, you might still find it cumbersome to identify the KMS keys that consume the largest amount of your request quota. When you receive the AWS KMS API charges that exceed your expectation, you can check the detailed billing usage in each AWS Region in Cost Explorer, but you cannot easily locate the KMS keys with the most API charges. This process becomes even more challenging when you manage a large number of KMS keys.

With the key-level API usage CloudWatch metrics, you can use the advanced metric query option to query CloudWatch Metrics Insights data with a user-friendly dialect of SQL to locate the KMS keys that consume the largest portion of the API usage quota or contribute the most API charges.

Walkthrough

To use Amazon CloudWatch Metrics Insights to identify the top 20 KMS keys that have the most cryptographic API usage up to the last 3 hours, complete the following steps:

  1. Open the CloudWatch console.
  2. In the navigation pane, choose Metrics, and then choose All metrics.
  3. Choose the Multi source query tab.
  4. For the data source, choose CloudWatch Metrics Insights.
  5. You can enter the following example query in Editor view:

    Note: In Builder view, the metric namespace, metric name, filter by, group by, order by, and limit options are shown. In Editor view, the same options as in Builder view are shown in query format.

    	SELECT SUM(SuccessfulRequest)
    	FROM SCHEMA("AWS/KMS", KeyArn, Operation)
    	GROUP BY KeyArn
    	ORDER BY MAX () DESC
    	LIMIT 20

  6. Choose Run in the Editor view or Graph query in the Builder view.

Example 2: How to set a new detailed alarm on unintentional runaway AWS KMS API usage

Running big data processing workflows that read Amazon Simple Storage Service (Amazon S3) files encrypted by KMS keys is a common scenario for analytics, business reporting, or machine learning projects. Typically, these workflows read a limited number of files from S3 on each invocation. However, misconfigured workflows could unintentionally read a large number of S3 files, which could result in exceeding your AWS KMS API request rate quotas or incurring undesirable charges due to spiky AWS KMS API usage. Historically, to address this issue, you would have had to build a customized alarm system by following these steps: 1) send AWS CloudTrail events generated by AWS KMS to Amazon CloudWatch Logs; 2) write queries in Amazon CloudWatch Logs Insights to track your API request usage; and 3) enable anomaly detection on the corresponding CloudWatch Log Insights math expression.

Now, with key-level API usage CloudWatch metrics, you can directly enable anomaly detection on these metrics to set up alarms for anomalous AWS KMS API usage patterns. This provides a more streamlined and efficient way to monitor and detect potential runaway workflows. By using these CloudWatch metrics and anomaly detection capabilities, you can proactively identify and address unintended increases in AWS KMS API usage, helping to avoid unexpected charges or service disruptions in your analytics, reporting, or machine learning pipelines.

Walkthrough

Consider a scenario where you have an analytics workflow that runs frequently, which uses the Decrypt AWS KMS API operation on a KMS key to decrypt and read data from S3. You would like to enable anomaly detection on the KMS key to trigger an alarm when the Decrypt call volume to the specific KMS key sees a discernible trend or pattern. To do so, complete the following steps:

  1. Open the CloudWatch console.
  2. In the navigation pane, choose Metrics, and then choose All metrics.
  3. Choose KMS, and then choose KeyArn, Operation.
  4. In the search bar, enter the Amazon Resource Name (ARN) of the key, and then choose Search. Select the CloudWatch metric you would like to enable anomaly detection for.
  5. Navigate to Graphed metrics, and using the Statistic and Period drop-down lists, choose the statistic and period that you would like to monitor. Then you can enable anomaly detection by selecting the Pulse icon.

    Figure 1: How to enable anomaly detection on a SuccessfulRequest metric

    Figure 1: How to enable anomaly detection on a SuccessfulRequest metric

  6. You can adjust the anomaly detection by setting the sensitivity to adjust the bandwidth, if needed.

    Figure 2: Anomaly detection is enabled on the SuccessfulRequest metric. The gray band illustrates the expected range of values and the anomaly is in red

    Figure 2: Anomaly detection is enabled on the SuccessfulRequest metric. The gray band illustrates the expected range of values and the anomaly is in red

Conclusion

This blog post highlighted the newly introduced key-level filtering capability for the AWS KMS API usage in CloudWatch. We showed two real-world use cases to demonstrate how you can use the new CloudWatch metrics. These use cases include improving operational visibility, setting up proactive alarms on anomalies in KMS API usage patterns, and potentially tracking detailed key usage for compliance purposes.

If you have feedback about this blog post, submit comments in the Comments section below. If you have questions about this blog post, start a new thread in the AWS Key Management Service re:Post.
 

Norman Li
Norman Li

Norman is a Software Development Manager for AWS KMS. In this role, Norman leads the development of visibility features, as well as internal scalability initiatives. Outside of work, Norman likes to spend time in the beautiful Pacific Northwest mountains.
Haiyu Zhen
Haiyu Zhen

Haiyu is a Senior Software Development Engineer for AWS KMS. She specializes in building secure, large-scale distributed systems and is passionate about enhancing cloud-native application security without compromising performance.

Develop and test AWS Glue 5.0 jobs locally using a Docker container

Post Syndicated from Subramanya Vajiraya original https://aws.amazon.com/blogs/big-data/develop-and-test-aws-glue-5-0-jobs-locally-using-a-docker-container/

AWS Glue is a serverless data integration service that allows you to process and integrate data coming through different data sources at scale. AWS Glue 5.0, the latest version of AWS Glue for Apache Spark jobs, provides a performance-optimized Apache Spark 3.5 runtime experience for batch and stream processing. With AWS Glue 5.0, you get improved performance, enhanced security, support for the next generation of Amazon SageMaker, and more. AWS Glue 5.0 enables you to develop, run, and scale your data integration workloads and get insights faster.

AWS Glue accommodates various development preferences through multiple job creation approaches. For developers who prefer direct coding, Python or Scala development is available using the AWS Glue ETL library.

Building production-ready data platforms requires robust development processes and continuous integration and delivery (CI/CD) pipelines. To support diverse development needs—whether on local machines, Docker containers on Amazon Elastic Compute Cloud (Amazon EC2), or other environments—AWS provides an official AWS Glue Docker image through the Amazon ECR Public Gallery. The image enables developers to work efficiently in their preferred environment while using the AWS Glue ETL library.

In this post, we show how to develop and test AWS Glue 5.0 jobs locally using a Docker container. This post is an updated version of the post Develop and test AWS Glue version 3.0 and 4.0 jobs locally using a Docker container, and uses AWS Glue 5.0 .

Available Docker images

The following Docker images are available for the Amazon ECR Public Gallery:

  • AWS Glue version 5.0 – ecr.aws/glue/aws-glue-libs:5

AWS Glue Docker images are compatible with both x86_64 and arm64.

In this post, we use public.ecr.aws/glue/aws-glue-libs:5 and run the container on a local machine (Mac, Windows, or Linux). This container image has been tested for AWS Glue 5.0 Spark jobs. The image contains the following:

To set up your container, you pull the image from the ECR Public Gallery and then run the container. We demonstrate how to run your container with the following methods, depending on your requirements:

  • spark-submit
  • REPL shell (pyspark)
  • pytest
  • Visual Studio Code

Prerequisites

Before you start, make sure that Docker is installed and the Docker daemon is running. For installation instructions, see the Docker documentation for Mac, Windows, or Linux. Also make sure that you have at least 7 GB of disk space for the image on the host running Docker.

Configure AWS credentials

To enable AWS API calls from the container, set up your AWS credentials with the following steps:

  1. Create an AWS named profile.
  2. Open cmd on Windows or a terminal on Mac/Linux, and run the following command:
PROFILE_NAME="profile_name"

In the following sections, we use this AWS named profile.

Pull the image from the ECR Public Gallery

If you’re running Docker on Windows, choose the Docker icon (right-click) and choose Switch to Linux containers before pulling the image.

Run the following command to pull the image from the ECR Public Gallery:

docker pull public.ecr.aws/glue/aws-glue-libs:5

Run the container

Now you can run a container using this image. You can choose any of following methods based on your requirements.

spark-submit

You can run an AWS Glue job script by running the spark-submit command on the container.

Write your job script (sample.py in the following example) and save it under the /local_path_to_workspace/src/ directory using the following commands:

$ WORKSPACE_LOCATION=/local_path_to_workspace
$ SCRIPT_FILE_NAME=sample.py
$ mkdir -p ${WORKSPACE_LOCATION}/src
$ vim ${WORKSPACE_LOCATION}/src/${SCRIPT_FILE_NAME}

These variables are used in the following docker run command. The sample code (sample.py) used in the spark-submit command is included in the appendix at the end of this post.

Run the following command to run the spark-submit command on the container to submit a new Spark application:

$ docker run -it --rm \
    -v ~/.aws:/home/hadoop/.aws \
    -v $WORKSPACE_LOCATION:/home/hadoop/workspace/ \
    -e AWS_PROFILE=$PROFILE_NAME \
    --name glue5_spark_submit \
    public.ecr.aws/glue/aws-glue-libs:5 \
    spark-submit /home/hadoop/workspace/src/$SCRIPT_FILE_NAME

REPL shell (pyspark)

You can run a REPL (read-eval-print loop) shell for interactive development. Run the following command to run the pyspark command on the container to start the REPL shell:

$ docker run -it --rm \
    -v ~/.aws:/home/hadoop/.aws \
    -e AWS_PROFILE=$PROFILE_NAME \
    --name glue5_pyspark \
    public.ecr.aws/glue/aws-glue-libs:5 \
    pyspark

You will see following output:

Python 3.11.6 (main, Jan  9 2025, 00:00:00) [GCC 11.4.1 20230605 (Red Hat 11.4.1-2)] on linux
Type "help", "copyright", "credits" or "license" for more information.
Setting default log level to "WARN".
To adjust logging level use sc.setLogLevel(newLevel). For SparkR, use setLogLevel(newLevel).
Welcome to
      ____              __
     / __/__  ___ _____/ /__
    _\ \/ _ \/ _ `/ __/  '_/
   /__ / .__/\_,_/_/ /_/\_\   version 3.5.2-amzn-1
      /_/

Using Python version 3.11.6 (main, Jan  9 2025 00:00:00)
Spark context Web UI available at None
Spark context available as 'sc' (master = local[*], app id = local-1740643079929).
SparkSession available as 'spark'.
>>> 

With this REPL shell, you can code and test interactively.

pytest

For unit testing, you can use pytest for AWS Glue Spark job scripts.

Run the following commands for preparation:

$ WORKSPACE_LOCATION=/local_path_to_workspace
$ SCRIPT_FILE_NAME=sample.py
$ UNIT_TEST_FILE_NAME=test_sample.py
$ mkdir -p ${WORKSPACE_LOCATION}/tests
$ vim ${WORKSPACE_LOCATION}/tests/${UNIT_TEST_FILE_NAME}

Now let’s invoke pytest using docker run:

$ docker run -i --rm \
    -v ~/.aws:/home/hadoop/.aws \
    -v $WORKSPACE_LOCATION:/home/hadoop/workspace/ \
    --workdir /home/hadoop/workspace \
    -e AWS_PROFILE=$PROFILE_NAME \
    --name glue5_pytest \
    public.ecr.aws/glue/aws-glue-libs:5 \
    -c "python3 -m pytest --disable-warnings"

When pytest finishes executing unit tests, your output will look something like the following:

============================= test session starts ==============================
platform linux -- Python 3.11.6, pytest-8.3.4, pluggy-1.5.0
rootdir: /home/hadoop/workspace
plugins: integration-mark-0.2.0
collected 1 item

tests/test_sample.py .                                                   [100%]

======================== 1 passed, 1 warning in 34.28s =========================

Visual Studio Code

To set up the container with Visual Studio Code, complete the following steps:

  1. Install Visual Studio Code.
  2. Install Python.
  3. Install Dev Containers.
  4. Open the workspace folder in Visual Studio Code.
  5. Press Ctrl+Shift+P (Windows/Linux) or Cmd+Shift+P (Mac).
  6. Enter Preferences: Open Workspace Settings (JSON).
  7. Press Enter.
  8. Enter following JSON and save it:
{
    "python.defaultInterpreterPath": "/usr/bin/python3.11",
    "python.analysis.extraPaths": [
        "/usr/lib/spark/python/lib/py4j-0.10.9.7-src.zip:/usr/lib/spark/python/:/usr/lib/spark/python/lib/",
    ]
}

Now you’re ready to set up the container.

  1. Run the Docker container:
$ docker run -it --rm \
    -v ~/.aws:/home/hadoop/.aws \
    -v $WORKSPACE_LOCATION:/home/hadoop/workspace/ \
    -e AWS_PROFILE=$PROFILE_NAME \
    --name glue5_pyspark \
    public.ecr.aws/glue/aws-glue-libs:5 \
    pyspark
  1. Start Visual Studio Code.
  2. Choose Remote Explorer in the navigation pane.
  3. Choose the container ecr.aws/glue/aws-glue-libs:5 (right-click) and choose Attach in Current Window.

  1. If the following dialog appears, choose Got it.

  1. Open /home/hadoop/workspace/.

  1. Create an AWS Glue PySpark script and choose Run.

You should see the successful run on the AWS Glue PySpark script.

Changes between the AWS Glue 4.0 and AWS Glue 5.0 Docker image

The following are major changes between the AWS Glue 4.0 and Glue 5.0 Docker image:

  • In AWS Glue 5.0, there is a single container image for both batch and streaming jobs. This differs from AWS Glue 4.0, where there was one image for batch and another for streaming.
  • In AWS Glue 5.0, the default user name of the container is hadoop. In AWS Glue 4.0, the default user name was glue_user.
  • In AWS Glue 5.0, several additional libraries, including JupyterLab and Livy, have been removed from the image. You can manually install them.
  • In AWS Glue 5.0, all of Iceberg, Hudi, and Delta libraries are pre-loaded by default, and the environment variable DATALAKE_FORMATS is no longer needed. Until AWS Glue 4.0, the environment variable DATALAKE_FORMATS was used to specify whether the specific table format is loaded.

The preceding list is specific to the Docker image. To learn more about AWS Glue 5.0 updates, see Introducing AWS Glue 5.0 for Apache Spark and Migrating AWS Glue for Spark jobs to AWS Glue version 5.0.

Considerations

Keep in mind that the following features are not supported when using the AWS Glue container image to develop job scripts locally:

Conclusion

In this post, we explored how the AWS Glue 5.0 Docker images provide a flexible foundation for developing and testing AWS Glue job scripts in your preferred environment. These images, readily available in the Amazon ECR Public Gallery, streamline the development process by offering a consistent, portable environment for AWS Glue development.

To learn more about how to build end-to-end development pipeline, see End-to-end development lifecycle for data engineers to build a data integration pipeline using AWS Glue. We encourage you to explore these capabilities and share your experiences with the AWS community.


Appendix A: AWS Glue job sample codes for testing

This appendix introduces three different scripts as AWS Glue job sample codes for testing purposes. You can use any of them in the tutorial.

The following sample.py code uses the AWS Glue ETL library with an Amazon Simple Storage Service (Amazon S3) API call. The code requires Amazon S3 permissions in AWS Identity and Access Management (IAM). You need to grant the IAM-managed policy arn:aws:iam::aws:policy/AmazonS3ReadOnlyAccess or IAM custom policy that allows you to make ListBucket and GetObject API calls for the S3 path.

import sys
from pyspark.context import SparkContext
from awsglue.context import GlueContext
from awsglue.job import Job
from awsglue.utils import getResolvedOptions


class GluePythonSampleTest:
    def __init__(self):
        params = []
        if '--JOB_NAME' in sys.argv:
            params.append('JOB_NAME')
        args = getResolvedOptions(sys.argv, params)

        self.context = GlueContext(SparkContext.getOrCreate())
        self.job = Job(self.context)

        if 'JOB_NAME' in args:
            jobname = args['JOB_NAME']
        else:
            jobname = "test"
        self.job.init(jobname, args)

    def run(self):
        dyf = read_json(self.context, "s3://awsglue-datasets/examples/us-legislators/all/persons.json")
        dyf.printSchema()

        self.job.commit()


def read_json(glue_context, path):
    dynamicframe = glue_context.create_dynamic_frame.from_options(
        connection_type='s3',
        connection_options={
            'paths': [path],
            'recurse': True
        },
        format='json'
    )
    return dynamicframe


if __name__ == '__main__':
    GluePythonSampleTest().run()

The following test_sample.py code is a sample for a unit test of sample.py:

The following test_sample.py code is a sample for a unit test of sample.py:
import pytest
from pyspark.context import SparkContext
from awsglue.context import GlueContext
from awsglue.job import Job
from awsglue.utils import getResolvedOptions
import sys
from src import sample


@pytest.fixture(scope="module", autouse=True)
def glue_context():
    sys.argv.append('--JOB_NAME')
    sys.argv.append('test_count')

    args = getResolvedOptions(sys.argv, ['JOB_NAME'])
    context = GlueContext(SparkContext.getOrCreate())
    job = Job(context)
    job.init(args['JOB_NAME'], args)

Appendix B: Adding JDBC drivers and Java libraries

To add a JDBC driver not currently available in the container, you can create a new directory under your workspace with the JAR files you need and mount the directory to /opt/spark/jars/ in the docker run command. JAR files found under /opt/spark/jars/ within the container are automatically added to Spark Classpath and will be available for use during the job run.

For example, you can use the following docker run command to add JDBC driver jars to a PySpark REPL shell:

$ docker run -it --rm \
    -v ~/.aws:/home/hadoop/.aws \
    -v $WORKSPACE_LOCATION:/home/hadoop/workspace/ \
    -v $WORKSPACE_LOCATION/jars/:/opt/spark/jars/ \
    --workdir /home/hadoop/workspace \
    -e AWS_PROFILE=$PROFILE_NAME \
    --name glue5_jdbc \
    public.ecr.aws/glue/aws-glue-libs:5 \
    pyspark

As highlighted earlier, the customJdbcDriverS3Path connection option can’t be used to import a custom JDBC driver from Amazon S3 in AWS Glue container images.

Appendix C: Adding Livy and JupyterLab

The AWS Glue 5.0 container image doesn’t have Livy installed by default. You can create a new container image extending the AWS Glue 5.0 container image as the base. The following Dockerfile demonstrates how you can extend the Docker image to include additional components you need to enhance your development and testing experience.

To get started, create a directory on your workstation and place the Dockerfile.livy_jupyter file in the directory:

$ mkdir -p $WORKSPACE_LOCATION/jupyterlab/
$ cd $WORKSPACE_LOCATION/jupyterlab/
$ vim Dockerfile.livy_jupyter

The following code is Dockerfile.livy_jupyter:

FROM public.ecr.aws/glue/aws-glue-libs:5 AS glue-base

ENV LIVY_SERVER_JAVA_OPTS="--add-opens java.base/java.lang.invoke=ALL-UNNAMED --add-opens=java.base/java.nio=ALL-UNNAMED --add-opens=java.base/sun.nio.ch=ALL-UNNAMED --add-opens=java.base/sun.nio.cs=ALL-UNNAMED --add-opens=java.base/java.util.concurrent.atomic=ALL-UNNAMED"

# Download Livy
ADD --chown=hadoop:hadoop https://dlcdn.apache.org/incubator/livy/0.8.0-incubating/apache-livy-0.8.0-incubating_2.12-bin.zip ./

# Install and configure Livy
RUN unzip apache-livy-0.8.0-incubating_2.12-bin.zip && \
rm apache-livy-0.8.0-incubating_2.12-bin.zip && \
mv apache-livy-0.8.0-incubating_2.12-bin livy && \
mkdir -p livy/logs && \
cat <<EOF >> livy/conf/livy.conf
livy.server.host = 0.0.0.0
livy.server.port = 8998
livy.spark.master = local
livy.repl.enable-hive-context = true
livy.spark.scala-version = 2.12
EOF && \
cat <<EOF >> livy/conf/log4j.properties
log4j.rootCategory=INFO,console
log4j.appender.console=org.apache.log4j.ConsoleAppender
log4j.appender.console.target=System.err
log4j.appender.console.layout=org.apache.log4j.PatternLayout
log4j.appender.console.layout.ConversionPattern=%d{yy/MM/dd HH:mm:ss} %p %c{1}: %m%n
log4j.logger.org.eclipse.jetty=WARN
EOF

# Switching to root user temporarily to install dev dependency packages
USER root 
RUN dnf update -y && dnf install -y krb5-devel gcc python3.11-devel
USER hadoop

# Install SparkMagic and JupyterLab
RUN export PATH=$HOME/.local/bin:$HOME/livy/bin/:$PATH && \
printf "numpy<2\nIPython<=7.14.0\n" > /tmp/constraint.txt && \
pip3.11 --no-cache-dir install --constraint /tmp/constraint.txt --user pytest boto==2.49.0 jupyterlab==3.6.8 IPython==7.14.0 ipykernel==5.5.6 ipywidgets==7.7.2 sparkmagic==0.21.0 jupyterlab_widgets==1.1.11 && \
jupyter-kernelspec install --user $(pip3.11 --no-cache-dir show sparkmagic | grep Location | cut -d" " -f2)/sparkmagic/kernels/sparkkernel && \
jupyter-kernelspec install --user $(pip3.11 --no-cache-dir show sparkmagic | grep Location | cut -d" " -f2)/sparkmagic/kernels/pysparkkernel && \
jupyter server extension enable --user --py sparkmagic && \
cat <<EOF >> /home/hadoop/.local/bin/entrypoint.sh
#!/usr/bin/env bash
mkdir -p /home/hadoop/workspace/
livy-server start
sleep 5
jupyter lab --no-browser --ip=0.0.0.0 --allow-root --ServerApp.root_dir=/home/hadoop/workspace/ --ServerApp.token='' --ServerApp.password=''
EOF

# Setup Entrypoint script
RUN chmod +x /home/hadoop/.local/bin/entrypoint.sh

# Add default SparkMagic Config
ADD --chown=hadoop:hadoop https://raw.githubusercontent.com/jupyter-incubator/sparkmagic/refs/heads/master/sparkmagic/example_config.json .sparkmagic/config.json

# Update PATH var
ENV PATH=/home/hadoop/.local/bin:/home/hadoop/livy/bin/:$PATH

ENTRYPOINT ["/home/hadoop/.local/bin/entrypoint.sh"]

Run the docker build command to build the image:

docker build \
    -t glue_v5_livy \
    --file $WORKSPACE_LOCATION/jupyterlab/Dockerfile.livy_jupyter \
    $WORKSPACE_LOCATION/jupyterlab/

When the image build is complete, you can use the following docker run command to start the newly built image:

docker run -it --rm \
    -v ~/.aws:/home/hadoop/.aws \
    -v $WORKSPACE_LOCATION:/home/hadoop/workspace/ \
    -p 8998:8998 \
    -p 8888:8888 \
    -e AWS_PROFILE=$PROFILE_NAME \
    --name glue5_jupyter  \
    glue_v5_livy

Appendix D: Adding extra Python libraries

In this section, we discuss adding extra Python libraries and installing Python packages using

Local Python libraries

To add local Python libraries, place them under a directory and assign the path to $EXTRA_PYTHON_PACKAGE_LOCATION:

$ docker run -it --rm \
    -v ~/.aws:/home/hadoop/.aws \
    -v $WORKSPACE_LOCATION:/home/hadoop/workspace/ \
    -v $EXTRA_PYTHON_PACKAGE_LOCATION:/home/hadoop/workspace/extra_python_path/ \
    --workdir /home/hadoop/workspace \
    -e AWS_PROFILE=$PROFILE_NAME \
    --name glue5_pylib \
    public.ecr.aws/glue/aws-glue-libs:5 \
    -c 'export PYTHONPATH=/home/hadoop/workspace/extra_python_path/:$PYTHONPATH; pyspark'

To validate that the path has been added to PYTHONPATH, you can check for its existence in sys.path:

Python 3.11.6 (main, Jan  9 2025, 00:00:00) [GCC 11.4.1 20230605 (Red Hat 11.4.1-2)] on linux
Type "help", "copyright", "credits" or "license" for more information.
Setting default log level to "WARN".
To adjust logging level use sc.setLogLevel(newLevel). For SparkR, use setLogLevel(newLevel).
Welcome to
      ____              __
     / __/__  ___ _____/ /__
    _\ \/ _ \/ _ `/ __/  '_/
   /__ / .__/\_,_/_/ /_/\_\   version 3.5.2-amzn-1
      /_/

Using Python version 3.11.6 (main, Jan  9 2025 00:00:00)
Spark context Web UI available at None
Spark context available as 'sc' (master = local[*], app id = local-1740719582296).
SparkSession available as 'spark'.
>>> import sys
>>> "/home/hadoop/workspace/extra_python_path" in sys.path
True

Installing Python packages using pip

To install packages from PyPI (or any other artifact repository) using pip, you can use the following approach:

docker run -it --rm \
    -v ~/.aws:/home/hadoop/.aws \
    -v $WORKSPACE_LOCATION:/home/hadoop/workspace/ \
    --workdir /home/hadoop/workspace \
    -e AWS_PROFILE=$PROFILE_NAME \
    -e SCRIPT_FILE_NAME=$SCRIPT_FILE_NAME \
    --name glue5_pylib \
    public.ecr.aws/glue/aws-glue-libs:5 \
    -c 'pip3 install snowflake==1.0.5; spark-submit /home/hadoop/workspace/src/$SCRIPT_FILE_NAME'

About the Authors

Author Headshot - Subramanya VajirayaSubramanya Vajiraya is a Sr. Cloud Engineer (ETL) at AWS Sydney specialized in AWS Glue. He is passionate about helping customers solve issues related to their ETL workload and implementing scalable data processing and analytics pipelines on AWS. Outside of work, he enjoys going on bike rides and taking long walks with his dog Ollie.

Noritaka Sekiyama is a Principal Big Data Architect on the AWS Glue team. He works based in Tokyo, Japan. He is responsible for building software artifacts to help customers. In his spare time, he enjoys cycling with his road bike.