The Agence du Numérique en Santé (ANS), the French governmental agency for health, introduced the HDS certification to strengthen the security and protection of personal health data. By achieving this certification, AWS demonstrates our continuous commitment to adhere to the heightened expectations for cloud service providers.
The following 24 Regions are in scope for this certification:
US East (Ohio)
US East (N. Virginia)
US West (N. California)
US West (Oregon)
Asia Pacific (Hong Kong)
Asia Pacific (Hyderabad)
Asia Pacific (Jakarta)
Asia Pacific (Mumbai)
Asia Pacific (Osaka)
Asia Pacific (Seoul)
Asia Pacific (Singapore)
Asia Pacific (Sydney)
Asia Pacific (Tokyo)
Canada (Central)
Europe (Frankfurt)
Europe (Ireland)
Europe (London)
Europe (Milan)
Europe (Paris)
Europe (Stockholm)
Europe (Zurich)
Israel (Tel Aviv)
Middle East (UAE)
South America (São Paulo)
The HDS certification demonstrates that AWS provides a framework for technical and governance measures to secure and protect personal health data according to HDS requirements. Our customers who handle personal health data can continue to manage their workloads in HDS-certified Regions with confidence.
AWS strives to continuously meet your architectural and regulatory needs. If you have questions or feedback about HDS compliance, reach out to your AWS account team.
To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.
If you have feedback about this post, submit comments in the Comments section below.
In this blog post, we show how you can integrate IAM Access Analyzer custom policy check capability into VS Code, so you can identify overly permissive IAM policies and fine-tune access controls early in the development process. This proactive approach to security and compliance helps to ensure that your IAM policies are validated before they are deployed, reducing the risk of introducing misconfigurations or granting unintended access. It also saves developer time by providing fast feedback to developers when they write a policy that does not meet organizational standards.
What is the problem?
Although security teams oversee an organization’s overall security posture, developers create applications that require specific permissions. To enable developers to work efficiently while maintaining high security standards, organizations often seek ways to safely delegate the authoring of AWS Identity and Access Management (IAM) policies to developers. Many AWS customers manually review developer-authored IAM policies before deploying them to production environments to help prevent granting excessive or unintended permissions. However, depending on the volume and complexity of policies, these manual reviews can be time-consuming, leading to development delays and potential bottlenecks in the deployment of applications and services. Organizations need to balance secure access management with the agility required for rapid application development and deployment.
How to use IAM Access Analyzer custom policy checks in VS Code
Custom policy checks are a feature in IAM Access Analyzer that are designed to help security teams proactively identify and analyze critical permissions within their IAM policies. In this section, we provide step-by-step instructions for using custom policy checks directly in VS Code.
Prerequisites
To complete the examples in our walkthrough, you first need to do the following:
Install Python version 3.6 or later.
Assuming you are already using the VS Code Integrated Development Environment (IDE), search for and install the AWS Toolkit extension.
So that you can open IAM Access Analyzer policy checks in the VS Code editor, open the VS Code Command Palette by pressing Ctrl+Shift+P, search for IAM Policy Checks, and then choose AWS: Open IAM Policy Checks as shown in Figure 1.
Figure 1: Search for the AWS: Open IAM Policy Checks option
By using the IAM policy checks option in VS Code, you can perform four types of checks:
We’ll walk through examples of each of these checks in the sections that follow.
Example 1: ValidatePolicy
In this example, we use the ValidatePolicy option provided by the IAM policy check plugin to validate IAM policies against IAM policy grammar and AWS best practices. When you run this check, you can view policy validation check findings that include security warnings, errors, general warnings, and suggestions for your policy. These actionable recommendations help you author policies that are aligned with AWS best practices.
To run the ValidatePolicy check
Let’s use the following IAM policy for illustration purposes. You can see that resource * (a wildcard) is being used in the first statement, which indicates that the iam:PassRole action is allowed for all resources.
In the VS Code editor, navigate to the IAM Policy Checks pane. Choose the document type JSON Policy Language and policy type Identity. Then choose Run Policy Validation.
Figure 2: IAM Access Analyzer ValidatePolicy check results
You can see that Access Analyzer has detected an issue, which is shown in the PROBLEMS pane.
Figure 3: Problems pane with finding details for the ValidatePolicy check
The security warning shown in Figure 3 states that the iam:PassRole action with a wildcard (*) in the resource can be overly permissive because it allows the ability to pass any IAM role in that account.
Now, let’s modify the IAM policy by replacing the wildcard (*) with a specific role Amazon Resource Name (ARN).
Verify the policy again by running the ValidatePolicy check to make sure that it doesn’t generate findings after you updated the IAM policy.
Figure 4: Results of the ValidatePolicy check after IAM policy correction
Example 2: CheckNoPublicAccess
With the CheckNoPublicAccess option, you can verify whether your resource policy grants public access for supported resource types.
To run the CheckNoPublicAccess check
To test whether a policy does not allow public access, create a new bucket using a CloudFormation template and attach a resource policy that grants access to any principal to see the objects in this bucket.
WARNING: This sample bucket policy should not be used in production. Using a wildcard in the principal element of a bucket policy would allow any IAM principal to view the contents of the bucket.
Select the document type CloudFormation template and then choose Run Custom Policy Check to see whether this resource policy passes the CheckNoPublicAccess check.
Figure 5: IAM Access Analyzer CheckNoPublicAccess check results
The policy check returns a failed result because this bucket does allow public access.
Figure 6: Problems pane finding details for CheckNoPublicAccess check
Next, fix this policy to allow access from a role within the same account by restricting the policy to a specific role ARN.
Re-run the CheckNoPublicAccess check. The resource policy no longer grants public access and the status of the policy check is PASS.
Example 3: CheckAccessNotGranted
The CheckAccessNotGranted option allows you to check whether a policy allows access to a list of IAM actions and resource ARNs. You can use this check to give developers fast feedback that certain permissions or access to certain resources are not allowed.
To run the CheckAccessNotGranted check
Identify sensitive actions and resources.
In the VS Code editor, under Custom Policy Checks, choose the check type CheckAccessNotGranted. Using a comma-separated list, create a list of actions and resource ARNs that you don’t want to allow in your IAM policy. You can also create a JSON file with your actions and resources by using the syntax shown in Figure 7. For this example, set the s3:PutBucketPolicy and dynamodb:DeleteTable IAM actions to “not allowed” in the IAM policy.
Figure 7: Configure the CheckAccessNotGranted check
Create a sample CloudFormation template that contains an IAM policy attached to an IAM role, as follows. This policy grants access to some of the actions that you deemed sensitive in Figure 7.
In the VS Code editor, choose Run Custom Policy Check to identify whether one of the sensitive actions or resources is allowed in the IAM policy. The policy check returns FAIL because the policy has the actions s3:PutBucketPolicy and dynamodb:DeleteTable, which you marked as actions that you don’t want developers to grant access to. Remove the restricted actions from the policy and run the check again to see a PASS result for the policy check.
Example 4: CheckNoNewAccess
The CheckNoNewAccess option is a custom policy check that verifies whether your policy grants new access compared to a reference policy.
You use a reference policy to check whether a candidate policy allows more access than the reference policy does. In other words, the check passes if the candidate policy is a subset of the reference policy. A reference policy typically starts by allowing all access. You then add a statement or statements that deny the access that you want the reference policy to check for. For more details and examples of reference policies, see the iam-access-analyzer-custom-policy-check-samples repository on GitHub.
The ability to use a reference policy provides you with the flexibility to look for almost anything in an IAM policy. This is useful when you have custom requirements for your organization that may not be met with some of the other custom policy checks.
To run the CheckNoNewAccess check
Create a reference policy: In your project, create a new JSON policy document that will serve as your reference policy.
The following reference policy checks that an IAM role trust policy only grants access to an allowlisted set of AWS services. This enables you to allow builders to create roles, but constrain the use of those roles to the set of AWS services specified.
In this reference policy, only the specified AWS service principals ec2.amazonaws.com, lambda.amazonaws.com, and ecs-tasks.amazonaws.com are allowed to assume the role.
Enter the reference policy in the VS Code editor. In the IAM Policy Checks pane, select the check type CheckNoNewAccess. Then set the reference policy type to Resource, because this is a trust policy that defines which principals can assume the role. In addition, provide the path of the reference policy that you created in Step 1. You can also directly enter the reference policy as a JSON policy document, as shown in Figure 8.
Figure 8: Enter the reference policy for the CheckNoNewAccess check
Create a CloudFormation template, as follows. This template creates an IAM role that allows the AWS service principals lambda.amazonaws.com and glue.amazonaws.com to assume the sample-application-role IAM role.
In the VS Code editor, choose Run Custom Policy Check to check your CloudFormation template against the reference policy you configured in Step 1. The check will return FAIL and you will see a security warning in the editor in the PROBLEMS pane.
Figure 9: Problems pane finding details for the CheckNoNewAccess check
The issue is that glue.amazonaws.com was not listed as a service principal that was allowed to assume a role in your reference policy. You can remove glue.amazonaws.com from the CloudFormation template and re-run the check to receive a PASS result.
Conclusion
In this post, we explored how you can use the integration of VS Code with IAM Access Analyzer in your development workflow to make sure that your IAM policies align with best practices and adhere to your organization’s security requirements. The four critical checks provided by IAM Access Analyzer can be summarized as follows:
The ValidatePolicy check provides actionable recommendations that help you author policies that are aligned with AWS best practices.
The CheckNoPublicAccess check helps protect resources from being exposed publicly and mitigates the risk of unauthorized public access.
The CheckAccesNotGranted check looks for specific IAM actions and resource ARNs to help enforce access restrictions and help prevent unauthorized access to critical data or services.
The CheckNoNewAccess check validates that the permissions granted in your IAM policies remain within the intended scope, as defined by your organization’s requirements.
AWS re:Invent 2024 was held in Las Vegas December 2–6, with over 54,000 attendees participating in more than 2,300 sessions and hands-on labs. The conference was a hub of innovation and learning hosted by AWS for the global cloud computing community.
In this blog post, we cover on-demand sessions and major security, identity, and compliance announcements that were unveiled leading up to and during the conference. Whether you missed the event or want to revisit the key takeaways, we’ve compiled the essential information for you to provide a comprehensive overview of the latest developments in AWS security, identity, and compliance. This year’s event put best practices for zero trust, generative AI–driven security, identity, and access management, DevSecOps, network and infrastructure security, data protection, and threat detection and incident response at the forefront.
Key announcements
For identity and access management, we launched multiple new features that can help you scale permissions management across your AWS Organizations.
Resource control policies (RCPs) – RCPs are a new type of organization policy that can be used to centrally create and enforce preventative controls on AWS resources in your organization. Using RCPs, you can centrally set the maximum available permissions to your AWS resources as you scale your workloads on AWS.
Centrally manage root access – With central management for root access, you now have a capability to centrally manage your root credentials, simplify auditing of credentials, and perform tightly scoped privileged tasks across your AWS member accounts managed using AWS Organizations.
Declarative policies – Declarative policies simplify the way you enforce durable intent, such as baseline configurations for AWS services within your organization.
Feature tiers – Amazon Cognito launched two user pool feature tiers: Essentials and Plus. The Essentials tier offers comprehensive and flexible user authentication and access control features, helping you to implement secure, scalable, and customized sign-up and sign-in experiences. The Plus tier offers threat protection capabilities against suspicious sign-ins for customers who have elevated security needs for their applications.
Developer-focused console – Amazon Cognito now offers a streamlined getting-started experience featuring a quick wizard and use case–specific recommendations. This approach helps you set up configurations and reach your end users faster and more efficiently than ever before.
Managed Login – This feature is a fully managed, hosted sign-in and sign-up experience that you can personalize to align with your company or application branding. Managed Login helps you offload the undifferentiated heavy lifting of designing and maintaining custom implementations such as passwordless authentication and localization.
Passwordless authentication – With passwordless authentication, you can secure user access to your application with passkeys, email, and text messages. If your users choose to use passkeys to sign in, they can do so using a built-in authenticator, such as Touch ID on Apple MacBooks and Windows Hello facial recognition on PCs.
To discover security issues in your environment, Amazon GuardDuty launched Extended Threat Detection, a capability that you can use to identify sophisticated, multi-stage threats targeting your AWS accounts, workloads, and data. You can now use new threat sequence findings that cover multiple resources and data sources over an extensive time period, allowing you to spend less time on first-level analysis and more time responding to critical severity threats to minimize business impact.
Amazon OpenSearch Service now offers a zero-ETL integration with Amazon Security Lake, enabling you to query and analyze security data in-place directly through OpenSearch Service. This integration allows you to efficiently explore voluminous data sources that were previously cost-prohibitive to analyze, helping you streamline security investigations and obtain comprehensive visibility of your security landscape. With the flexibility to selectively ingest data and without the need to manage complex data pipelines, you can now focus on effective security operations while potentially lowering your analytics costs.
AWS Security Incident Response is a new service that helps you respond to security issues in your environment. This new service combines the power of automated monitoring and investigation, accelerated communication and coordination, and direct 24/7 access to the AWS Customer Incident Response Team to quickly prepare for, respond to, and recover from security events.
In the zero trust space, AWS Verified Access AWS Verified Accessand Amazon VPC Lattice both launched support for accessing non-HTTPS resources. Verified Access enables you to provide secure, VPN-less access to your corporate applications over protocols such as TCP, SSH, and RDP. With the launch of VPC Resources for Amazon VPC Lattice, you can now access your application dependencies through a VPC Lattice service network. You’re able to connect to your application dependencies that are hosted in different VPCs, accounts, and on-premises using additional protocols, including TLS, HTTP, HTTPS, and now TCP. Watch the on demand session to learn how you can enable zero trust access over non-HTTP(S) protocols by using AWS Verified Access.
Amazon Route 53 Resolver DNS Firewall launched an advanced firewall rule that has a new set of capabilities that you can use to monitor and block suspicious DNS traffic associated with advanced DNS threats.
Amazon Virtual Private Cloud launched block public access, which is a one-click declarative control that admins can implement centrally to authoritatively block internet traffic for each of their VPCs.
As more and more customers deploy generative AI workloads into production, it’s important to have proper security controls. Amazon Bedrock launched two new features to help with this:
Automated Reasoning checks – Automated Reasoning checks help detect hallucinations and provide a verifiable proof that a large language model response is accurate. With Automated Reasoning checks, domain experts can more straightforwardly build specifications called Automated Reasoning Policies that encapsulate their knowledge in fields such as operational workflows and HR policies. Users of Amazon Bedrock Guardrails can validate generated content against an Automated Reasoning Policy to identify inaccuracies and unstated assumptions, and explain why statements are accurate in a verifiable way.
Multimodal toxicity detection (Preview) – Amazon Bedrock Guardrails now supports multimodal toxicity detection for image content, enabling organizations to apply content filters to images. This capability, now in public preview, removes the heavy lifting required to build your own safeguards for image data or spend cycles with manual evaluation that can be error-prone and tedious.
AWS has continued to work closely with partners to help drive customer success. There were three new partner programs launched at AWS re:Invent:
AI Security category – The AI Security category in the AWS Security competency helps you identify AWS Partners with deep experience securing AI environments and defending AI workloads against advanced threats. Partners in this category are validated for their capabilities in areas such as prevention of sensitive data disclosure, prevention of injection threats, security posture management, and implementing responsible AI filtering.
AWS Security Incident Response Specialization – Today, AWS customers rely on various third-party tools and services to support their internal security incident response capabilities. To better help both customers and partners, AWS introduced AWS Security Incident Response, a new service that helps you prepare for, respond to, and recover from security events. Alongside approved AWS Partners, AWS Security Incident Response monitors, investigates, and escalates triaged security findings from Amazon GuardDuty and other threat detection tools through AWS Security Hub. Security Incident Response is designed to identify and escalate only high-priority incidents.
Amazon Security Lake Ready Specialization – This specialization recognizes AWS Partners who have technically validated their software solutions to integrate with Amazon Security Lake and demonstrated successful customer deployments. These solutions have been technically validated by AWS Partner Solutions Architects for their sound architecture and proven customer success.
Experience content on demand
If you were unable to join us in person or you want to watch a session again, you can view the sessions that are available on demand. Catch the CEO Keynote with Matt Garman to learn how AWS is reinventing foundational building blocks in addition to developing brand-new experiences, all to empower AWS customers and partners with what they need to build a better future. You can also replay additional re:Invent 2024 keynotes.
Watch the Security Innovation Talk, with AWS CISO Chris Betz, to hear how the latest AWS innovations are helping customers move fast and stay secure. Learn how AWS empowers organizations to confidently integrate and automate security into their products, services, and processes so security teams can focus their time on work that brings the highest value to the business. Chris also shares how AWS is helping to make the internet more secure by scaling security innovation and investing in the security community.
Stream any of the AWS security, identity, and compliance breakout sessions and new launch talks on demand to learn about the following key topics, and more:
Consider joining us for more in-person security learning opportunities by saving the date for AWS re:Inforce 2025, which will take place June 16–18 in Philadelphia, Pennsylvania. We look forward to seeing you there!
If you want to discuss how these new announcements can help your organization improve its security posture, AWS is here to help. Contact your AWS account team today.
Amazon Cognito is a developer-centric and security-focused customer identity and access management (CIAM) service that simplifies the process of adding user sign-up, sign-in, and access control to your mobile and web applications. Cognito is a highly available service that supports a range of use cases, from managing user authentication and authorization to enabling secure access to your APIs and workloads. It’s a managed service that can act as an identity provider (IdP) for your applications, can scale to millions of users, provides advanced security features, and can support identity federation with third-party IdPs.
A feature of Amazon Cognito is support for OAuth 2.0 client credentials grants, used for machine-to-machine (M2M) authorization. As your M2M use cases scale, it becomes important to have proper monitoring, optimization of token issuance, and awareness of security best practices and considerations. It’s a best practice for app clients to locally cache and reuse access tokens while still valid and not expired. You can customize how long issued tokens are valid, so it’s important to make sure that the timeframe is aligned with your security requirements. If caching and reusing access tokens isn’t possible at the client level or cannot be enforced, then combining your M2M use cases with a REST API proxy integration using Amazon API Gateway enables you to cache token responses. By using API Gateway caching, you can optimize the request and response of access tokens for M2M authorization. This reduces redundant calls to Cognito for access tokens, thus improving the overall performance, availability, and security of your M2M use cases.
In this post, we explore strategies to help monitor, optimize, and secure Amazon Cognito M2M authorization. You’ll first learn some effective monitoring techniques to keep track of your usage, then delve into optimization strategies using API Gateway and token caching. Lastly, we will cover security best practices and considerations to bolster the security of your M2M use cases. Let’s dive in and discover how to make the most out of your Amazon Cognito M2M implementation.
Machine-to-machine authorization
Amazon Cognito uses an OAuth 2.0 client credentials grant to handle M2M authorization. A Cognito user pool can issue a client ID and client secret to allow your service to request a JSON web token (JWT)-compliant access token to access protected resources. Figure 1 illustrates how an app client requests an access token using the client credentials grant flow with Amazon Cognito.
Figure 1: Client credentials grant flow
The client credential grant flow (Figure 1) includes the following steps:
The app client makes an HTTP POST request to the Amazon Cognito user pool /token endpoint (see The token issuer endpoint for more information), which provides an authorization header consisting of the client ID and client secret, and request parameters consisting of grant type, client ID, and scopes.
After validating the request, Cognito will return a JWT-compliant access token.
The client can make subsequent requests to a downstream resource server using the Cognito issued access token.
The resource server gets a JSON Web Key Set (JWKS) from the Cognito user pool. The JWKS contains the user pool’s public keys, which should be used to verify the token signature.
The resource server uses the public key to verify the signature of the access token is valid (proving the token has not been tampered with). The resource server also needs to verify that the token is not expired and required claims and values are present, including scopes. The resource server should use the aws-jwt-verify library to verify that the access token is valid.
After the access token is verified and the app client is authorized, the requested resource is returned to the app client.
Now, let’s dive deep into the monitoring, optimization, and security considerations around M2M authorization with Amazon Cognito.
Monitoring usage and costs
In May 2024, Amazon Cognito introduced pricing for M2M authorization to support continued growth and expand M2M features. Customer accounts using M2M with Cognito prior to May 9, 2024, are exempt from M2M pricing until May 9, 2025 (for more information, see Amazon Cognito introduces tiered pricing for machine-to-machine (M2M) usage). To get better visibility into your existing Amazon Cognito usage types, you can use the Security tab of the Cost and Usage Dashboards Operations Solution (CUDOS) dashboard. This dashboard is part of the Cloud Intelligence Dashboard, an opensource framework that provides AWS customers actionable insights and optimization opportunities at an organization scale. As shown in Figure 2, the Security tab in the CUDOS dashboard provides visuals that show the cost and spend of Amazon Cognito per usage type and the projected cost for M2M app clients and token requests after the exemption period with daily granularity. This daily breakdown allows you to track how your cost optimization efforts are trending.
Figure 2: Example Amazon Cognito spend and projected cost with daily granularity
You can also see the monthly spend per account for each usage type, as shown in Figure 3.
Figure 3: Example Amazon Cognito spend and projected cost per AWS account
You can see the usage and spend per resource ID of user pools contributing to the cost, as shown in Figure 4. This resource-level granularity enables you to identify the top spending user pool and prioritize usage and cost management efforts accordingly. An interactive demo of this dashboard is available. For more information, see Cloud Intelligence Dashboards.
Figure 4: Example Amazon Cognito resource usage and cost by resource ID, account, and AWS Region
In addition to using the CUDOS dashboard to help understand Cognito M2M usage and costs, you can also request fine-grained usage details down to the app client level. This can include the number of access tokens successfully requested per app client and the last time the app client was used to issue tokens. To understand fine-grained app client usage, you need to make sure that token requests include the client_id request query parameter. This will result in an AWS CloudTrail log event that includes the client ID within the additionalEventData JSON object that is associated with the client credentials token request, as shown in Figure 5.
Figure 5: Sample CloudTrail event log including client_id
You can also use an Amazon CloudWatch log group to capture and store your CloudTrail logs for longer retention and analysis. Then using CloudWatch Logs Insights, you can use the following sample query to gather app client usage.
fields additionalEventData.userPoolId as user_pool_id, additionalEventData.requestParameters.client_id.0 as client_id, eventName, additionalEventData.responseParameters.status
| filter additionalEventData.requestParameters.grant_type.0="client_credentials" and eventName="Token_POST" and additionalEventData.responseParameters.status="200"
| stats count(*) as count, latest(eventTime) as last_used by user_pool_id, client_id
| sort count desc
Figure 6 is an example result from the preceding CloudWatch Logs Insights query. The result includes the user_pool_id, client_id, count, and last_used columns. The total number of successful token requests grouped per user pool and client ID will be displayed in the count column and the last time the app client successfully issued an access token will be displayed in the last_used column.
Figure 6: Example screenshot result set from CloudWatch Logs Insights query
Optimizing token requests
Now that you know how to better monitor your Amazon Cognito usage and costs, let’s dive deeper into how to optimize your token requests usage. For M2M, it’s recommended that clients use mechanisms to locally cache access tokens to use for authorization. This will reduce the need for the client to request a new access token until the previously issued token is no longer valid. However, the environment where the client runs could be hosted by an external third party or owned by a different team and as the resource owner, you won’t have control over whether the third party implements token caching at the client side. If this is a scenario that you have, you can use a HTTP proxy integration to cache the access token using API Gateway. Because the M2M use case follows the client credentials grant flow of the OAuth 2.0 specification, the /token endpoint of your user pool is what will be configured with the API Gateway proxy integration. This proxy integration is where caching in API Gateway can be used. With caching, you can reduce the number of token requests made to your user pool /token endpoint and improve the latency of the client receiving a cached token in the response. With caching, you can achieve additional benefits, such as cost optimization, improved performance efficiency, higher levels of availability, and custom domain flexibility.
Solution overview
Figure 7: Token caching solution
The solution (shown in the Figure 7) includes the following steps.
The client makes an HTTP POST request to an API Gateway REST API.
The API Gateway method request caches the scope URL query string parameter and the Authorization HTTP request header as caching keys. The integration request is configured as a proxy to the /oauth2/token endpoint of your Amazon Cognito user pool.
Cognito validates the request, making sure that the client ID and client secret are correct from the authorization header, a valid client ID has been provided as a query string parameter, and the client is authorized for the requested scopes.
If the request is valid, Cognito returns an access token to the gateway through the integration response. With caching enabled, the response from the HTTP integration (Cognito token endpoint) is cached for the specified time-to-live (TTL) period.
The method response of the gateway returns the access token to the client.
Subsequent token requests with a remaining cached TTL will be returned, using the authorization header and scope as the caching keys.
To set up token caching, follow the steps in Managing user pool token expiration and caching. After a valid token request is returned through the API Gateway proxy integration and cached, subsequent token requests to the proxy that match the caching keys (authorization header and scope parameter) will return that same access token. This token will be returned to the client until the TTL of the cached token has expired. It’s recommended to set the TTL of the cache to be a few minutes less than the TTL of the access token issued from Amazon Cognito. For example, if your security posture requires access tokens to be valid for 1 hour, then set your caching TTL to be a few minutes less than the 1-hour token validity. It’s also important to understand the ideal caching capacity for your use case. The caching capacity affects the CPU, memory, and network bandwidth of the cache instance within the gateway. As a result, the cache capacity can affect the performance of your cache. See Enable Amazon API Gateway caching for more information. For information about how to determine the ideal cache capacity for your use case, see How do I select the best Amazon API Gateway Cache capacity to avoid hitting a rate limit?. Let’s now explore some security best practices and considerations to raise the security bar of your M2M use cases.
Security best practices
Now that you know how to monitor Amazon Cognito M2M usage and costs and how to optimize access token requests, let’s review some security best practices and considerations. Using OAuth 2.0 client credentials grant for M2M authorization helps protect your APIs. One of the key factors for this is that the access token used by the client to connect to the resource server is a temporary and time-bound token. The client must obtain a new access token after its previous token has expired so you won’t have to issue long-lived credentials that are used directly between the client and the resource server. The client ID and client secret remain confidential on the client and are only used between the client and the Amazon Cognito user pool to request an access token.
Use AWS Secrets Manager
If the workload is running on AWS, use AWS Secrets Manager so you don’t have to worry about hard-coding credentials into workloads and applications. If the workload is running on premises or through another provider, then use a similar secrets’ vault or privileged access management solution to house the workload credentials. The workload should retrieve credentials for authentication only at runtime.
Use AWS WAF
It’s a security best practice to use AWS WAF to protect your Amazon Cognito user pool endpoints. This can help protect your user pools from unwanted HTTP web requests by forwarding selected non-confidential headers, request body, query parameters, and other request components to an AWS WAF web access control list (ACL) associated with your user pool. By using AWS WAF, you can also add managed rule groups to your user pool, such as the AWS managed rule group for Bot Control, to add protection against automated bots that can consume excess resources, cause downtime, or perform malicious activities. Learn more about how to associate an AWS WAF Web ACL with your Cognito user pool.
Always verify tokens
After a client has obtained an access token, it’s important to make sure the client is authorized to access the requested resources. If the resource is using API Gateway and the built-in Amazon Cognito authorizer, then the integrity of the token, the signature, and token expiration are checked and validated for you. However, if you require a more custom authorization decision with API Gateway, you can use an AWS Lambda authorizer along with the aws-jwt-verify library. By doing so, you can verify that the signature of the JWT token is valid, make sure that the token isn’t expired, and that the necessary and expected claims are present (including necessary scopes). For more fine-grained authorization decisions, look into using Amazon Verified Permissions with the resource server or even within a Lambda authorizer. If the resource server is an external system that is, outside of AWS or a custom resource server, you want to make sure that the access token is validated and verified before the requested resources are returned to the client.
Define scopes at the app client level
It’s important to carefully define and constrain the scope of access for each app client to align with the principle of least privilege. By restricting each client ID to only the necessary scopes, organizations can minimize the risk of issuing access tokens with more access and permissions than is required. If your use case aligns with M2M multi-tenancy, consider creating a dedicated app client per tenant and using defined custom scopes for that tenant. Remember that the number of M2M app clients is a pricing dimension and will incur a cost. See Custom scope multi-tenancy best practices for more information.
Security considerations
If you’re using API Gateway to proxy token requests and caching access tokens, the following are some security considerations to raise the security bar of your M2M workload.
Allow token requests only through an API Gateway proxy
After your API Gateway proxy integration is configured and set up for optimization and you have AWS WAF configured for your user pool, you can add an additional layer of security by using an allow list so that only requests from your API Gateway proxy to your Amazon Cognito user pool are accepted. For this, inject a custom HTTP header within the integration request of the POST method execution and create an allow rule within your web ACL that looks for that specific header. You will also create an additional web ACL rule to block all traffic. The single allow rule will have a priority order of 0 and the block-all-traffic rule will have a priority order of 1. Ultimately, this will block all requests that go directly to your Cognito user pool /token endpoint and only allow requests that have been made through the API Gateway proxy. Figure 8 that follows is a deeper explanation of this setup.
Figure 8: Token caching solution with AWS WAF
The process shown in Figure 8 has the following steps:
The client makes a direct HTTP POST call to the /oauth2/token endpoint of the Amazon Cognito user pool. This request would be denied by the AWS WAF web ACL deny all rule.
The client initiates an OAuth2 client credentials grant (HTTP POST) against an API Gateway stage (/token).
The REST API gateway is a proxy integration to the /oauth2/token endpoint of the Cognito user pool.
Within the integration request settings, configure a custom header (for example, x-wafAuthAllowRule). Treat the value of this header as a secret that remains only within the API Gateway integration request and is not exposed outside of the gateway.
Consider using Lambda, Amazon EventBridge, and AWS Secrets Manager to automatically rotate this header value in both the API Gateway integration request and in the AWS WAF web ACL rule.
The request is proxied to the Cognito /oauth2/token endpoint and AWS WAF is configured to protect the Cognito user pool endpoints and therefore web ACL rules are evaluated.
The custom header from the integration request (the preceding step) is evaluated against the web ACL rules to allow this request.
Cognito will verify the authorization header (containing the client ID and client secret) and requested scopes.
After successful credential validation, an access token is returned to the gateway within the integration response.
The access token is cached using the following caching keys:
Authorization header.
Scope query string parameter.
The access token is returned to the client through API Gateway.
Subsequent token requests with a remaining cached TTL are returned to client immediately, using the authorization header and scope as the caching keys.
Additional authorizer with API Gateway
Using the client credentials grant is designed to obtain an access token so that an app client can access downstream resources. If you’re using API Gateway as a proxy integration to your token endpoint, as described previously, you can also use a separate authorizer with an API Gateway proxy. Therefore, to begin the OAuth 2.0 client credentials grant flow, a separate authorization takes place first. For example, if you’re in a highly regulated industry, you might require the use of mTLS authentication to obtain an access token. This might seem like a double-authentication scenario; however, this helps prevent unauthenticated attempts against your API Gateway proxy integration to get an access token from Amazon Cognito.
Encrypting the API cache
While configuring your API Gateway proxy integration and provisioning your API cache, you can enable encryption of the cached response data. Because this caches access tokens for the set TTL of your choosing, you should consider encrypting this data at rest if necessary to help meet your security requirements. You can use the default method caching or set an override stage-level caching and enable encryption at rest.
Conclusion
In this post, we shared how you can monitor, optimize, and enhance the security posture of your machine-to-machine (M2M) authorization use cases with Amazon Cognito. This involved using the Cost and Usage Dashboards Operations Solution (CUDOS) to understand your Cognito M2M token requests and costs. We also discussed using caching from Amazon API Gateway as an HTTP proxy integration to the Cognito user pool /oauth2/token endpoint. By following the guidance in this post, you can better understand your M2M usage and costs and achieve added benefits such as cost optimization, performance efficiency, and higher levels of availability. Lastly, we provided several security best practices and considerations that can be used as additional layers to elevate your security posture.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on Amazon Cognito re:Post or contact AWS Support.
Securing an event of the magnitude of AWS re:Invent—the Amazon Web Services annual conference in Las Vegas—is no small feat. The most recent event, in December, operated on the scale of a small city, spanning seven venues over twelve miles and nearly seven million square feet across the bustling Las Vegas Strip.
Keeping all 60,000 in-person attendees, 400,000 online participants, and their data secure requires a sophisticated blend of physical and logical security measures—a challenge that we’ve addressed by building an integrated security strategy that brings both sides together. We used every resource available to us, including drones, K9 units, our network security teams, and much more, to help protect every person attending the event and their data.
Figure 1: The re:Invent Command Post
Security is a team sport
At Amazon, our physical security and information security (logical) teams work together to secure our customers, employees, and infrastructure across our diverse range of businesses at scale against a wide range of threats. At large events such as re:Invent, this integrated approach allows us to protect the many aspects of our event—from our attendees, to our on-site computers and servers, to our Wi-Fi network and its users—as comprehensively as possible.
Amazon doesn’t work alone, either. Our event security teams coordinate with Las Vegas Metropolitan Police and over 40 different agencies, including counterterrorism, bomb squad personnel, and first responders.
Figure 2: K9 units – valued members of our onsite security team
These teams are co-located in the Command Post—the nerve center of our security operations. Here, physical and logical security converge as nearly every element of our security footprint comes together, and we monitor the event for threats in real-time. This includes our event security management teams, our intelligence team, and our CCTV camera operators, alongside local law enforcement and emergency management services. As an added layer of protection, we also operate a dedicated Wireless Security Operations Center (WiSOC) in close coordination with our main Command Post, which serves as the primary hub for our wireless and cybersecurity teams.
Fostering open dialogue and information-sharing is critical for effective collaboration to secure re:Invent. And as the threat landscape continues to evolve, organizations must prioritize closing the gap between physical and logical security. Not only is this integrated approach the key to effectively securing a city-sized event such as re:Invent, but it also helps us protect our customers, employees, and company every day.
City-scale security
We deploy a number of integrated security measures at re:Invent to protect our physical and digital assets. When it comes to physical security, the primary concern is, of course, human safety. At re:Invent, we deploy thousands of security personnel, including guards, K9 units, and first responders to help respond to and assist with any issues, such as medical events, fires, theft, or overcrowding. We have CCTV cameras stationed in high-traffic areas and implement strict access control measures, including walkthrough screening detectors at entry points and a robust credentialing system, to create a safe and secure environment for our attendees.
We also have help from drones. The automated, high-flying craft provide a bird’s eye view at re:Play—the culminating concert at the Las Vegas Festival Grounds—and help coordinate responses to issues. Using AWS cloud solutions, live footage is streamed directly to our onsite security teams to monitor crowd flow.
Figure 3: A security team member showcases a drone used to help secure re:Play
We’re also focused on the security of our network, which in turn protects its users—our attendees. Our wireless and cybersecurity teams work to identify anomalous activity across our network, including signs of spoofing—a tactic where actors set up look-a-like Wi-Fi networks in an attempt to lure attendees to connect to their network instead of ours.
Amazon also secures the presentations given by re:Invent’s cloud computing and AI experts, executives, and engineers. To have confidence in sharing their insights, speakers must know that their talks run on secure, uninterrupted channels streaming to hundreds of thousands of viewers around the world. Our re:Invent mobile app is built with security in mind, too, so attendees have a safe place to manage events and in-conference needs.
Our integrated approach to security is made possible by the AWS Cloud, which helps us support the different components of our security operation and share critical information rapidly. Whether we’re facing a logical security threat, physical security concern, or a wellness incident, our success hinges on our response time—and running our operations in the AWS Cloud enables us to move quickly.
Amazon will continue investing in and strengthening our unified approach to help make sure that, no matter the vector of the threat, our teams will have a cohesive, unified response. We’re proud to be a leader in this space and hope our learnings can help others enhance their own security resilience, both inside and outside of events.
This comprehensive course is designed to help security professionals, architects, and artificial intelligence and machine learning (AI/ML) engineers understand and implement security best practices for generative AI applications and models in the AWS Cloud.
AWS Skill Builder is a learning center for AWS customers and partners to build cloud skills through digital trainings, self-paced labs, and other course types. AWS Skill Builder has a variety of AWS security content to help customers understand concepts and gain hands-on experience with AWS security.
The course highlights are as follows:
Introduction to the Generative AI Security Scoping Matrix – Learn how to categorize and secure different AI implementations by using this innovative framework.
Coverage of key AI security frameworks – Gain insights into the OWASP Top 10 for Large Language Models (LLMs) and the MITRE ATLAS framework.
Practical security strategies – Develop skills to implement comprehensive security across the areas of governance, legal, risk, controls, and resilience for various AI scopes.
Real-world applications – Apply security concepts to case studies covering consumer applications, enterprise solutions, pre-trained models, fine-tuned models, and self-trained models.
We value your feedback and contributions. If you have thoughts or insights about the course after completing it, please share them in the Comments section below or contact AWS Support.
AWS Identity and Access Management Access Analyzer simplifies inspecting unused access to guide you towards least privilege. You can use unused access findings to identify over-permissive access granted to AWS Identity and Access Management (IAM) roles and users in your accounts or organization. From a delegated administrator account for IAM Access Analyzer, you can use the dashboard to review unused access findings across your organization and prioritize the accounts to inspect based on the volume and type of findings. The findings highlight unused roles, unused access keys for IAM users, and unused passwords for IAM users. For active IAM users and roles, the findings provide visibility into unused services and actions. Recently, IAM Access Analyzer launched new configuration capabilities that you can use to customize the analysis. You can select accounts, roles, and users to exclude, and focus on the areas that matter the most to you. You can use identifiers such as account ID or scale configuration using tags. By scoping the IAM Access Analyzer to monitor a subset of accounts and roles, you can reduce noise from unwanted findings. You can update the configuration when needed to change the scope of analysis. With this new offering, IAM Access Analyzer provides enhanced controls to help you tailor the analysis more closely to your organization’s security needs.
In this post, we walk you through an example scenario. Imagine that you’re a cloud administrator in a company that uses Amazon Web Services (AWS). You use AWS Organizations to organize your workload into several organizational units (OUs) and accounts. You have dedicated accounts for testing and experimenting with new AWS features called sandbox accounts across your organization. The sandbox accounts can be created by anyone in your company and are centrally recorded. You’re using tags on IAM resources and have followed AWS best practices and strategies when tagging your AWS resources. Tags are applied to the IAM roles created by your teams.
To make sure that your teams are following the principle of least privilege and are working with only the required permissions to access the AWS accounts, you use IAM Access Analyzer. You created an unused access analyzer at the organization level so it will monitor the AWS accounts in your organization. You noticed that you have multiple unused access findings. After analysis, your security team suggests the exclusion of some AWS accounts, IAM roles, and users so they can focus on the relevant findings. They want the sandbox accounts and the IAM roles they use for security purposes (such as auditing, incident response) to be excluded from the unused access analysis.
You can select accounts and roles to exclude when you create a new analyzer or update the analyzer later. In this post, we show you how to configure IAM Access Analyzer unused access finding to exclude specific accounts across your organization and specific principals (IAM roles and IAM users) once you have set up an analyzer. There is no additional pricing for using the prescriptive recommendations after you have enabled unused access findings.
Prerequisites
The following are the prerequisites to configure IAM Access Analyzer for unused access analysis:
An unused access analyzer created at the organization level
Administrative level access to the IAM Access Analyzer delegated administrator account
A list of account IDs that you want to exclude
IAM roles with tags
In the following sections, you will learn how to customize your IAM Access Analyzer to better suit your organization’s needs. This includes the following:
Explore how to exclude specific AWS accounts from the analyzer’s unused access findings.
See how to exclude tagged IAM roles from the analysis, allowing you to focus on the most relevant security insights and you see how to review exclusions on your analyzer to modify them as needed.
By the end, you will have a tailored unused access analyzer that provides more meaningful and actionable results for your organization.
Exclude specific accounts across your organization
In this section, you will see how to update your existing unused access analyzer at the organization level through the AWS Management Console and AWS Command Line Interface (AWS CLI) to exclude specific AWS account IDs from its analysis.
If you don’t have an unused access analyzer in the organization, see this post for instructions on how to create one.
Use the console to update your unused access analyzer:
Connect to your IAM Access Analyzer delegated administrator account (by default, your organization management account).
Open the IAM Access Analyzer console in your management account. You will see the dashboard with your active finding by selecting the analyzer of your choice on the top right. In this example, the analyzer has 251 active findings.
Figure 1: Unused access findings dashboard without exclusions
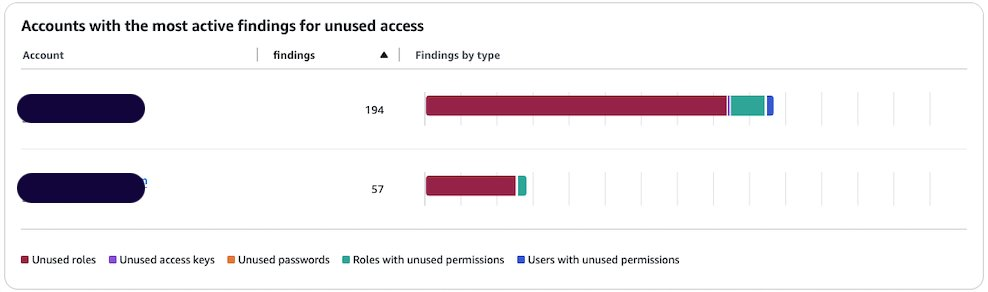
You can see the split of active findings per account. The example account has 57 active findings that you want to exclude from it.
Figure 2: Unused access findings per account
Select Analyzer settings under Access Analyzer in that navigation pane.
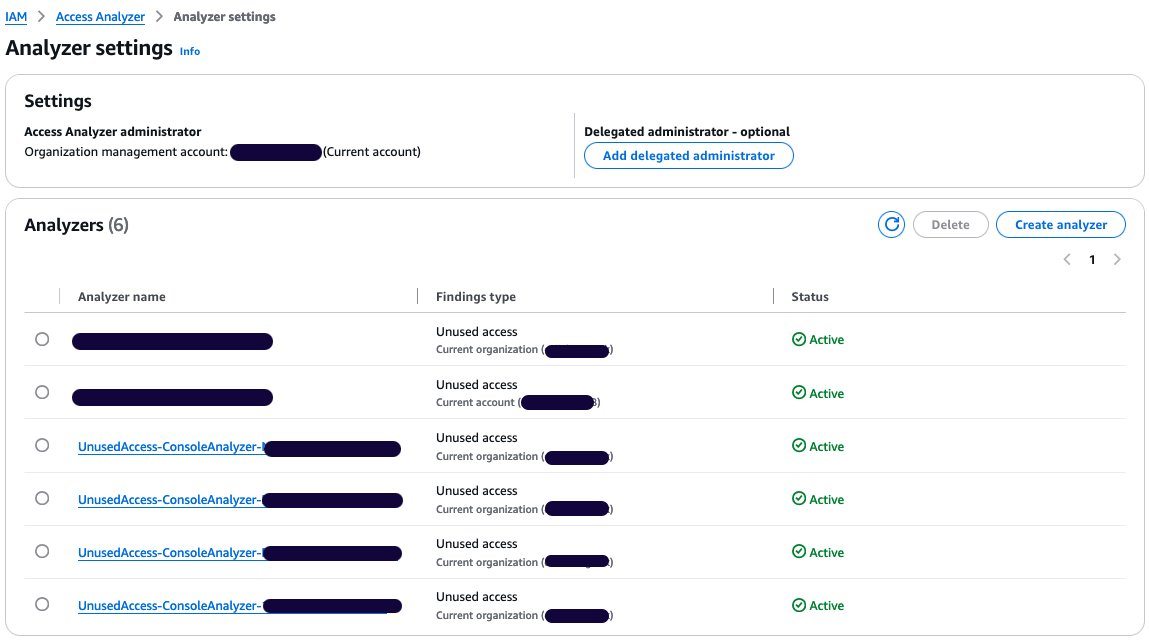
The analyzer settings page presents the analyzers in your AWS Region and their status.
Select your unused access analyzer in the list based on its name.
Figure 3: Active access analyzers
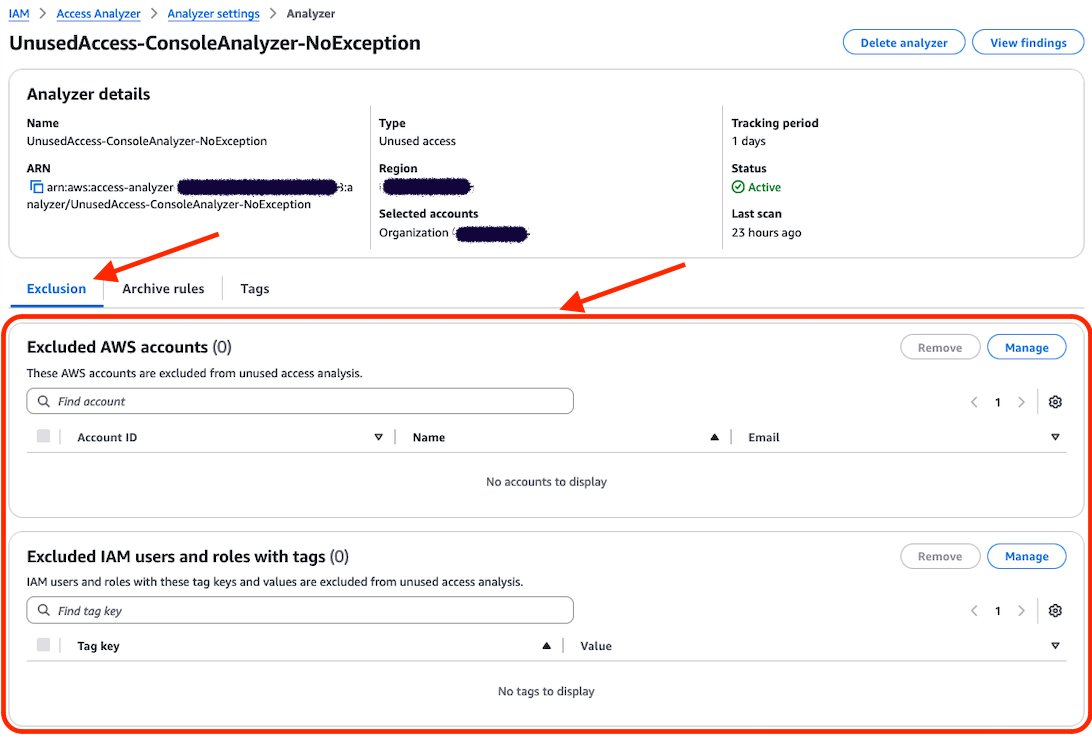
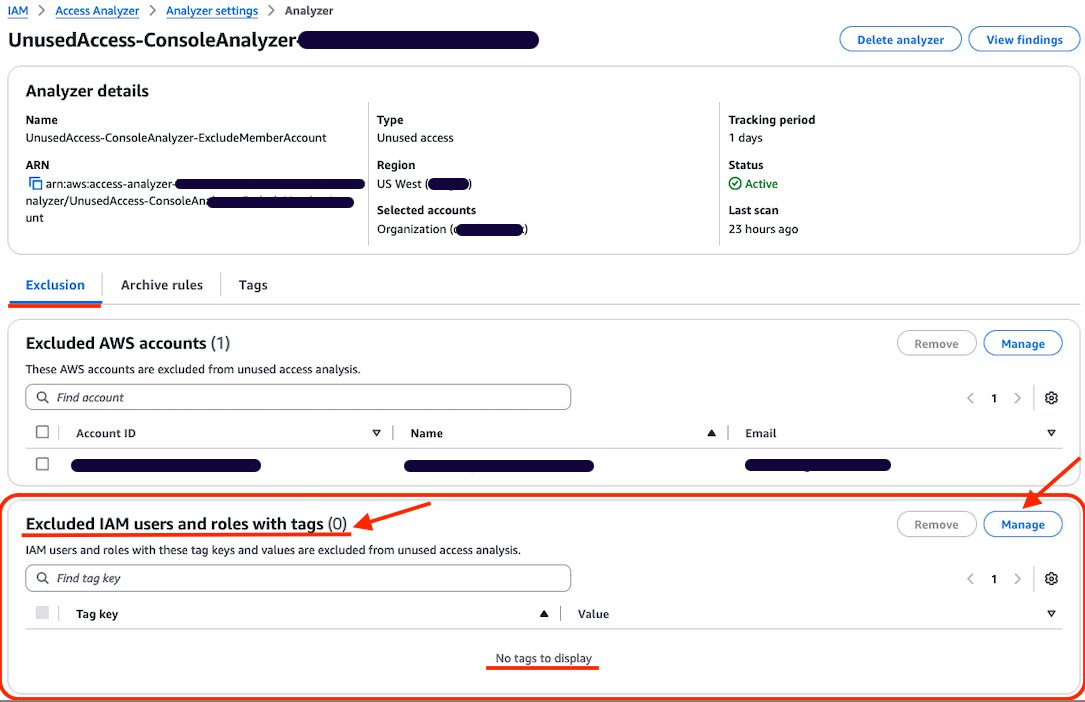
On the Analyzer page, you can see the analyzer settings and a new tab called Exclusion. Because you have no excluded AWS accounts, the count of Excluded AWS accounts is 0 and there are no accounts displayed.
Figure 4: Unused access analyzer exclusion tab
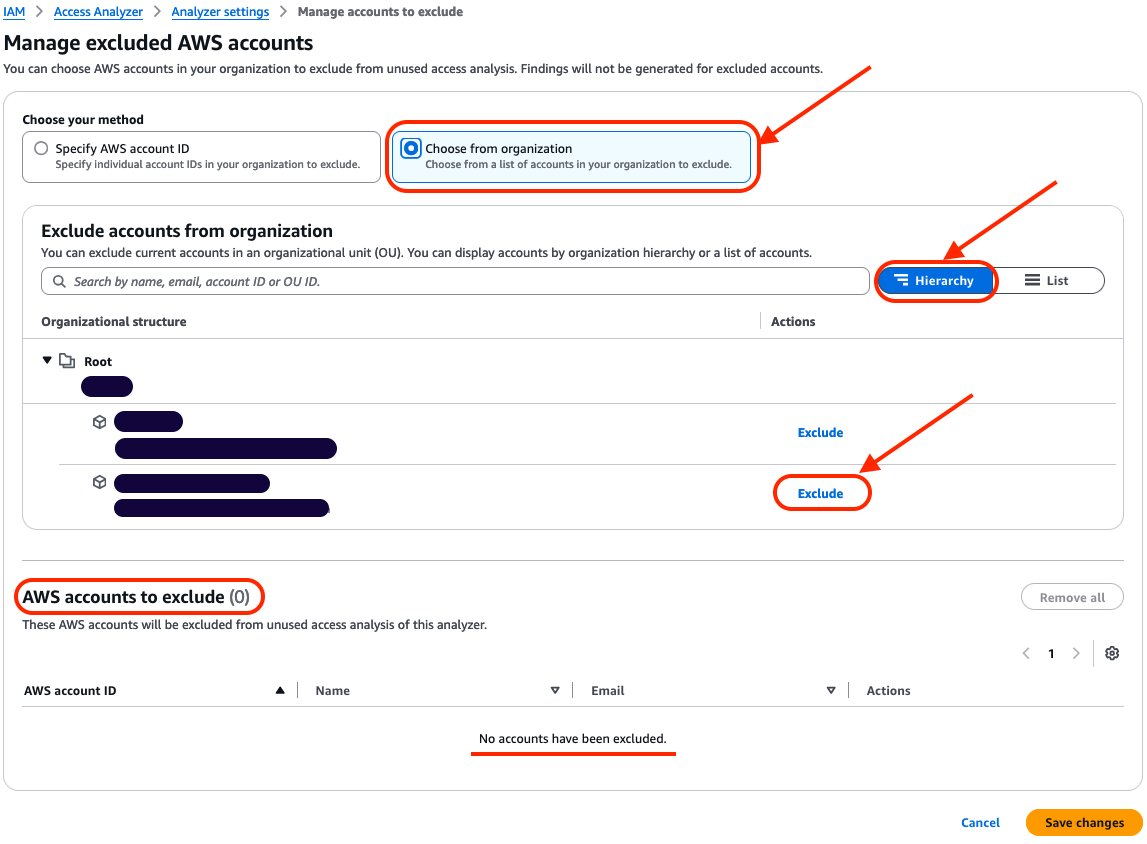
Choose Manage in the Excluded AWS accounts section.
Select Choose from organization and Hierarchy and choose Exclude next to the sandbox account that you want to exclude.
Figure 5: Exclude sandbox account
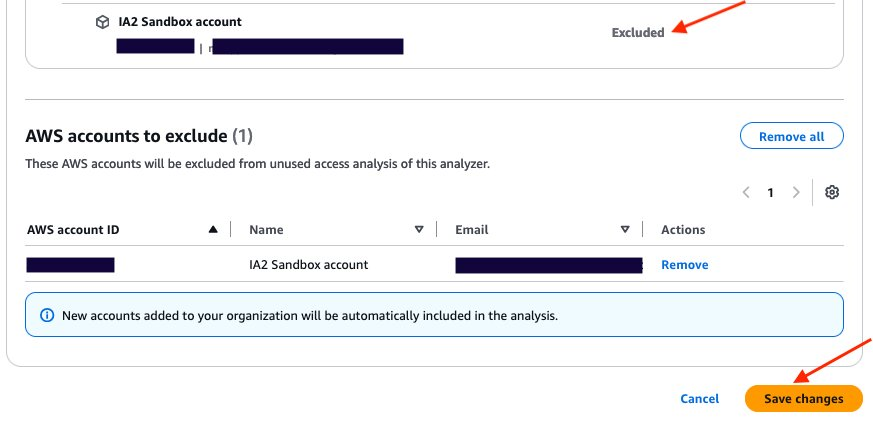
After you select Exclude for the sandbox account, the account will be deselected and will appear in AWS accounts to exclude. The count of accounts to exclude has changed from 0 to 1. After you have finished, choose Save changes.
Figure 6: Verify that the account is excluded and save changes
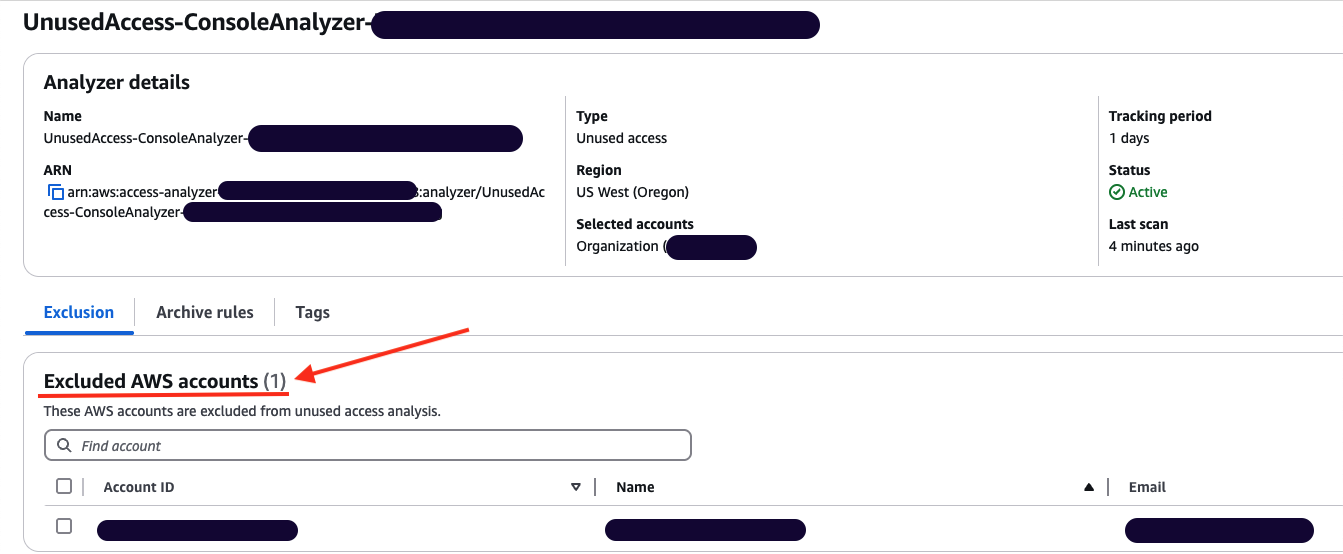
The page will be automatically updated with your changes. You can then review the Excluded AWS accounts and verify that your excluded account is correctly configured.
Figure 7: Analyzer configuration updated with excluded account
You can go back to the console dashboard and see the results. In this example, the exclusion of the sandbox account has caused the total number of active findings to go down from 251 to 194.
Figure 8: Dashboard showing a reduction in active findings
Use AWS CLI to update your unused access analyzer:
You can update your existing analyzer using the AWS CLI command aws accessanalyzer update-analyzer. Use the following command, replacing <YOUR-ANALYZER-NAME> with the name of your analyzer.
You have successfully excluded a sandbox account from the unused access analysis. Now you will exclude the IAM roles used by the security team to audit your accounts based on tags.
Excluding specific principals in your organization using tags
In this section, you will see how to update an existing unused access analyzer by excluding tagged IAM roles in your organization using the console and then AWS CLI.
Use the console to update your unused access analyzer:
Open the IAM Access Analyzer console.
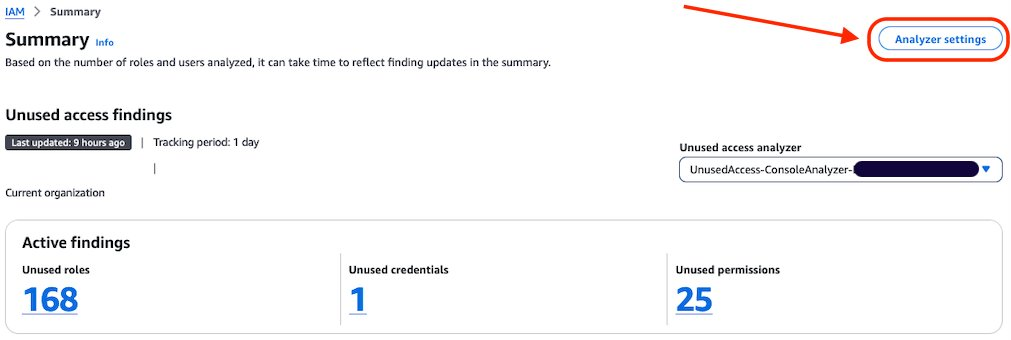
Review the summary dashboard containing your unused findings. Choose Analyzer settings at the top of the screen.
Figure 9: IAM Access Analyzer summary dashboard
You will see a list of analyzers created in your account in that Region. Select the analyzer that you want to update.
Review the analyzer page. On the Exclusion tab, you will see Exclude IAM users and roles with tags with a count of 0.
Figure 10: Configure exclusion of IAM roles using tag
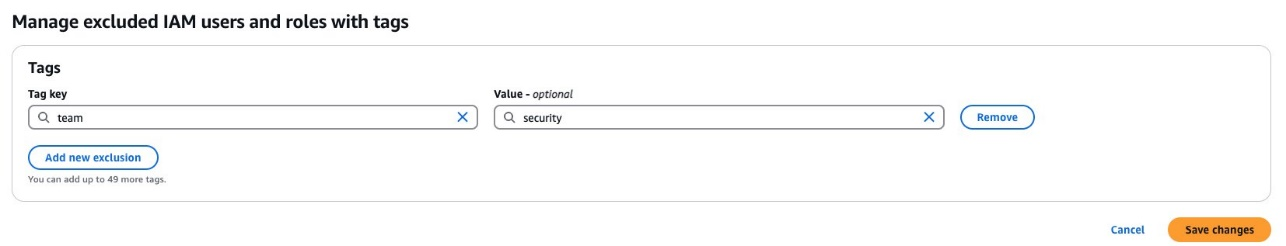
Choose Manage in the Excluded IAM users and roles with tags section.
Add the tags attached to the roles that you want to exclude from the analysis and choose Save changes.
Figure 11: Add tag to exclude
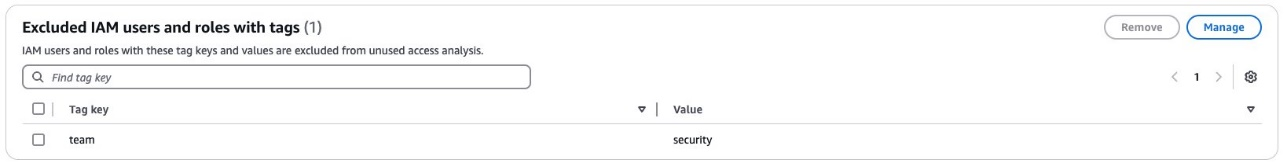
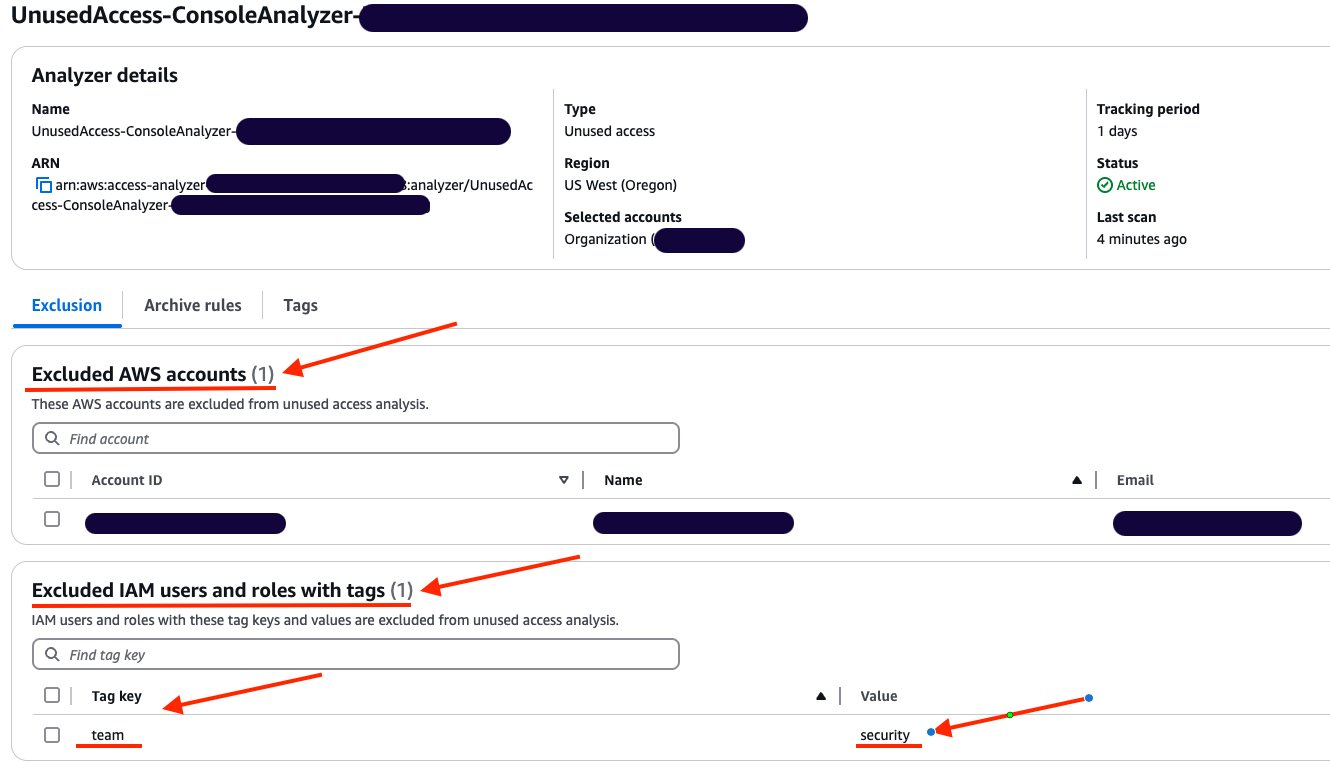
You can now see that Excluded IAM users and roles with tags now has a count of 1, and you can see the tags in the list.
Figure 12: List of exclusion tags
Use AWS CLI to update your unused access analyzer:
You can also update your existing analyzer using the AWS CLI command aws accessanalyzer update-analyzer. Using the following command, replace <YOUR-ANALYZER-NAME> with the name of your analyzer.
You can review, remove, or update the exclusions configured on your analyzer by using the console or AWS CLI. For example, as a security administrator managing multiple accounts, you might initially exclude IAM roles that have the tag security from analysis. However, you might need to review these exclusions if your policies change, requiring analysis of certain security roles or removing the exclusion entirely. By adjusting your exclusions, you can make sure that your analyzer’s results remain relevant to your organization’s needs and account structure.
Review the exclusion on unused access analyzer using the console:
In this section, review the tags that have been excluded from an analyzer.
Open the IAM console.
Select Access Analyzer, under Access reports, you will see a summary dashboard of findings from an analyzer.
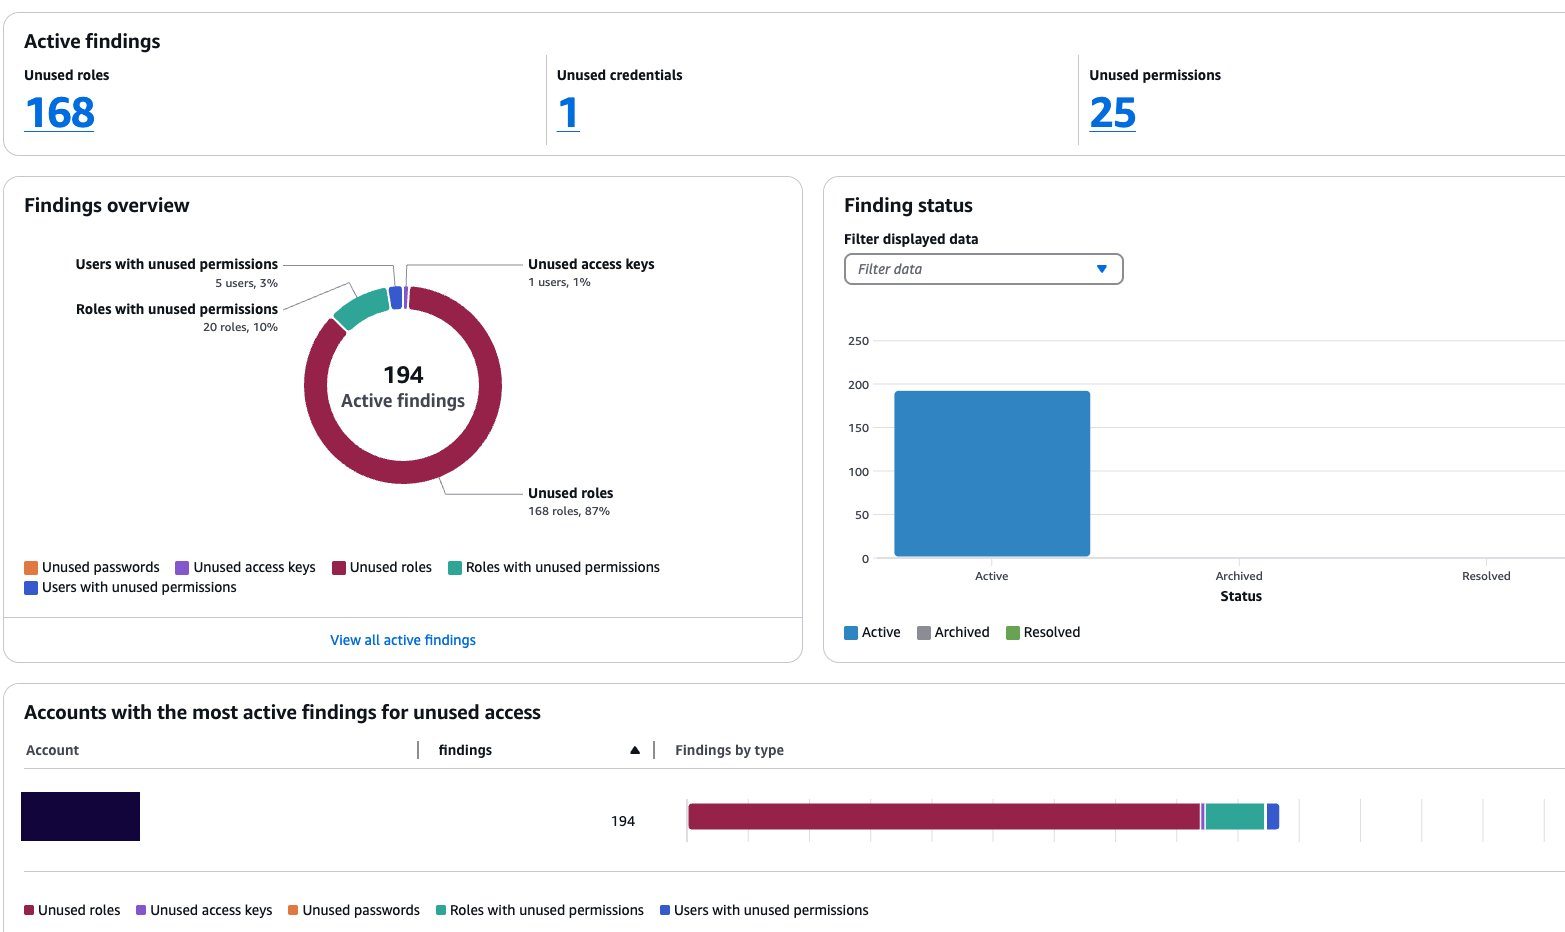
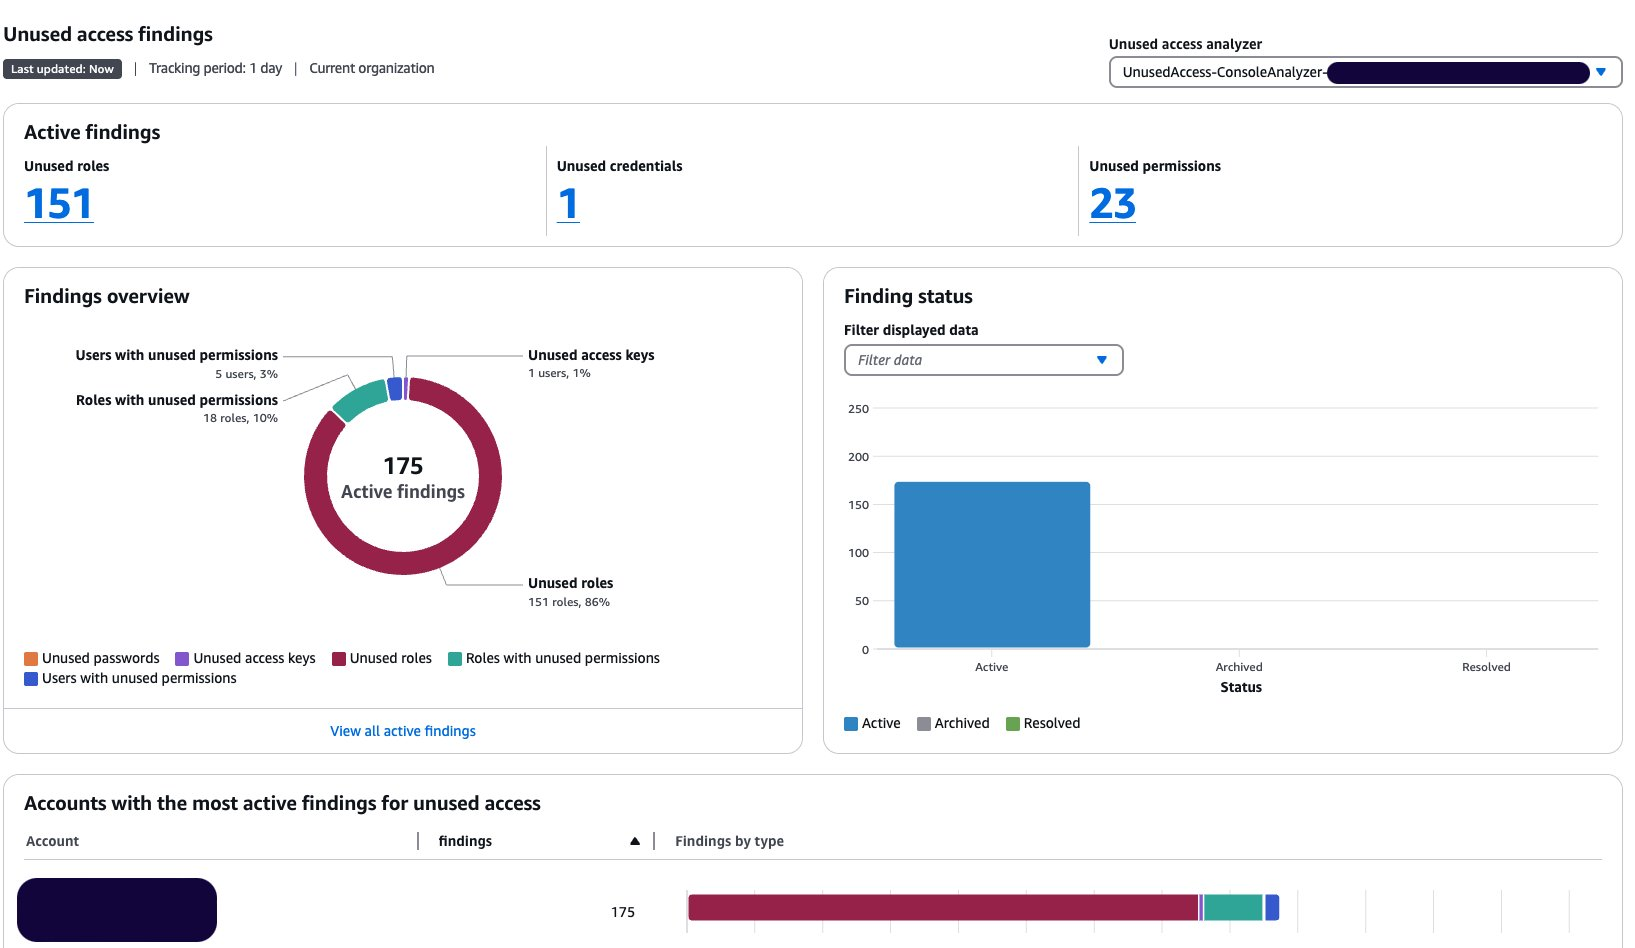
The Active findings section shows the number of active findings for unused roles, the number of active findings for unused credentials and the number of active findings for unused permissions.
The Findings overview section includes a breakdown of the active findings.
The Findings status section shows the status of findings (whether active, archived or resolved).
Figure 13: Unused access analyzer dashboard
Select the Analyzer settings at the top of the screen.
Select the analyzer that you want to review to see the exclusion tags.
After applying the tags, the updated dashboard is shown after the next scan.
Figure 15: Dashboard showing reduction of findings after exclusions
Review the exclusion on an unused access analyzer using AWS CLI:
Using the name of your analyzer, you can run the command get-analyzer to see the configured exclusion. Using the following command, replace <YOUR-ANALYZER-NAME> with the name of your analyzer:
In this post, you learned how to tailor your unused access analyzer to your needs by excluding specific accounts and IAM roles. To exclude the accounts in your organization from being monitored by IAM Access Analyzer, you can use a list of account IDs or select them from a hierarchical view of your organization structure. You can exclude IAM roles and IAM users based on tags. By customizing the exclusion on the unused access analyzer, you saw that the number of active findings went down, helping you focus on the findings that matter most. With this new offering, IAM Access Analyzer provides enhanced controls to help you tailor the analysis more closely to your organization’s security needs.
Amazon Web Services (AWS) re:Invent drew nearly 60,000 attendees from across the globe to Las Vegas, Nevada, December 2–6, 2024. The conference featured 5 keynotes, 18 innovation talks, and 1,900 sessions and hands-on labs offering immersive learning and networking opportunities.
With dozens of service and feature announcements, and innumerable best practices shared by AWS executives, customers, and partners—summarizing highlights isn’t easy. Three themes caught my attention: generative artificial intelligence (AI), digital sovereignty, and security.
Generative AI
The impact of generative AI was a central focus, as emphasized by Dr. Swami Sivasubramanian, Vice President of Data and AI at AWS, during his re:Invent keynote. The convergence of massive data sets and specialized compute made available through the cloud have created the perfect conditions for artificial intelligence to flourish. New tools and interfaces are enabling widespread adoption at an unprecedented pace, driving efficiency and unlocking creativity for all of us.
People’s expectations for applications are changing with generative AI. Organizations need more than just a chatbot or a single, powerful large language model (LLM) as they look to innovate and enhance customer experiences.
In their innovation talk, Architectural methods and breakthroughs in innovative apps in the cloud, Shaown Nandi, Director of Technology, and Ben Cabanas, Asia Pacific Director of Technology at AWS, showcased generative AI and advancements in developer tools. These advancements are transforming application design and removing the undifferentiated heavy lifting, empowering you to modernize systems and develop robust data strategies.
Nandi and Cabanas, along with leaders at Intuit, Anz Bank, and Siemens, explored three areas of cloud architecture (shown in Figure 1). These areas can give you the leverage you need to amplify the impact of your developers and data with cutting-edge techniques and breakthrough technologies like generative AI.
Figure 1: Three focus areas to gain leverage and accelerate solutions
Many of the announcements made during re:Invent are designed to help you meet real-world challenges, and gain the leverage you need to be successful as you build and scale transformative generative AI applications. The next generation of Amazon SageMaker, Amazon Nova foundation models (FMs), new Amazon Q capabilities, Amazon Bedrock Guardrails Automated Reasoning checks, and the task governance capability in Amazon SageMaker HyperPod are just a few of the new products and features you can use to increase agility, build trust, and control costs as you accelerate AI initiatives.
Digital sovereignty challenges and the technical measures, operational controls, and contract protections AWS offers to address them also featured prominently during the conference.
Customers are increasingly focused on maintaining control of their data and being able to meet regulatory requirements anywhere they operate. Digital sovereignty is emerging as a top priority, especially in the European Union.
In his breakout session, Digital sovereignty: overcome complexity and enable future-readiness, Max Peterson, Vice President of Sovereign Cloud at AWS, noted that digital sovereignty can mean different things to different organizations. Countries and regions around the world have their own requirements, and there is no uniform guidance around the types of workloads, industries, or sectors that need to meet them. Key challenges (depicted in Figure 2) include data residency, operator access restrictions, resilience and survivability, and independence and transparency—all of which are rooted in trust.
Figure 2: Digital sovereignty challenges
End users entrust organizations with sensitive information, and they need to feel confident that it’s handled safely and ethically. They expect the services they rely on to be secure, simple-to-use, and available. Likewise, the organizations that are building those services to store data need to trust the infrastructure they’re building on. They have to be able to provide assured proof that data and privacy are protected, and that control over data remains in the hands of those with the proper authority.
There is no one-size-fits-all approach to driving innovation while meeting digital sovereignty requirements. However, with AWS you can achieve the full benefits of the cloud while maintaining control over where you locate your data, who can access it, and how it’s used.
Peterson highlighted the AWS Nitro System that powers AWS Regions for trusted and confidential computing, and generative AI and machine learning (ML) innovations such as Amazon Bedrock. AWS sovereign cloud offerings range from encryption services to the new AWS European Sovereign Cloud (planned for Q4 2025). These offerings facilitate the control and choice you need to overcome data sovereignty challenges. They also balance the benefits of emerging technologies with the need to keep up with the evolving requirements of citizens and customers.
Raising the bar on security was an overarching theme. Chris Betz, CISO at AWS, set the tone during his innovation talk, Security insights and innovation from AWS, noting that security is the single most important expectation AWS customers have. We continuously invest in our security culture—working hard to help you do the same. Betz underscored the effectiveness of our Security Guardians program, which provides the tools, resources, and guidance developers need to address security considerations at each stage of development, and launch products that are Secure by Design. The program, Betz pointed out, has accelerated secure development and improved overall security at scale at AWS.
Watch Betz’s innovation talk to hear how Commonwealth Bank of Australia used a similar approach to support its DevSecOps transformation, and visit the AWS Security Blog to find out how you can build your own Security Guardians program.
Noteworthy announcements included AWS Security Incident Response, a new service that provides automated triage, coordinated communication, and expert guidance to help you streamline security event responses and recover from cybersecurity threats.
Not surprisingly, the subject of end-to-end encryption (E2EE) also grabbed attention in the wake of the ongoing breach of telecommunication networks by a state-sponsored threat actor known as Salt Typhoon. Because unauthorized parties may have access to unencrypted texts and phone calls, the Cybersecurity and Infrastructure Security Agency (CISA) and the Federal Bureau of Investigation (FBI) are advising Americans to start using encrypted messaging apps to protect text and voice communications.
In the breakout session How the U.S. Army uses AWS Wickr to secure mission-critical comms, Gabe Chiulli, Cloud CTO, and Christopher Watts, Cloud Services Division Chief at U.S. Army, highlighted how the U.S. Army Enterprise Cloud Management Agency uses AWS Wickr to allow users to chat freely while protecting sensitive communications.
Wickr helps organizations in all industries secure one-to-one and group messaging, voice and video calling, file sharing, screen sharing, and location sharing with 256-bit E2EE. Data residency controls allow you to host conversations in the region of your choice, and your technical teams can build and deploy Wickr Bot integrations to bring AWS ML and generative AI services to edge devices in a simple chatbot interface. Additionally, unlike consumer messaging apps, Wickr offers the data retention and administrative controls needed to help meet recordkeeping requirements, and manage user and device data remotely.
It’s clear that generative AI will continue to expand technology horizons, and reshape customer experiences. Digital sovereignty needs will evolve with regulations, increasing efforts to maintain control over data. And security, as always, remains top-of-mind.
AWS re:Invent 2024 introduced new capabilities, best practices, and strategic partnerships to help you innovate and address challenges in these areas. It was an awe-inspiring experience, and I can’t wait to see what re:Invent 2025 will bring!
For more information about product announcements during AWS re:Invent, visit the AWS News Blog and AWS Blog hub.
To watch keynotes, innovation talks, and breakout sessions on demand, visit the conference website.
Amazon Macie is a managed service that uses machine learning (ML) and deterministic pattern matching to help discover sensitive data that’s stored in Amazon Simple Storage Service (Amazon S3) buckets. Macie can detect sensitive data in many different formats, including commonly used compression and archive formats. However, Macie doesn’t support the discovery of sensitive data within images, audio, video, or other types of multimedia content. Customers often ask how to effectively detect whether there’s sensitive data in images. This can be a significant challenge for organizations, especially those operating in highly regulated industries with strict data protection requirements.
In this post, we show you how to gain visibility of sensitive data embedded in images that are stored within your S3 buckets by adding an additional conversion layer to extract image-based data into a format supported by Macie. The solution also uses the recommended set of managed identifiers and custom data identifiers supported by Macie to cover most use cases.
Solution overview
In this section, we walk through the components of the solution. The solution is deployed using AWS Serverless Application Model (AWS SAM), which is an open source framework for building serverless applications. AWS SAM helps to organize related components and operate on a single stack. When used together with the AWS SAM CLI, it’s a useful tool for developing, testing, and building serverless applications on AWS. We provided an AWS SAM template that you can use to set up the required services and AWS Lambda functions. Figure 1 illustrates the architecture of the solution.
Figure 1: Solution architecture and workflow
The solution workflow is as follows:
A user uploads images that might contain sensitive data into the S3 bucket.
After you have verified that potentially sensitive data has been uploaded into the S3 bucket, you can manually invoke the Lambda function textract-trigger to start the process. This function calls Amazon Textract asynchronously to process files in the S3 bucket with filename extensions such as .png, .jpg, and .jpeg. Amazon Textract creates a job for each image and extracts the text found in each image.
Because the operation is asynchronous, the job ID and status of each call is stored in an Amazon DynamoDB table to track the status of jobs and make sure that all of the jobs are completed before Macie is triggered to scan the S3 bucket.
The resulting JSON file from the Amazon Textract job is stored within the same S3 bucket as the original image.
For each analysis job, Amazon Textract sends a job completion notification to the registered Amazon Simple Notification Service (Amazon SNS) topic AmazonTextractJobSNSTopic. The Lambda function macie-trigger is subscribed to the SNS topic and triggered every time an SNS message is received for a completed Amazon Textract analysis job.
Further post-processing is done by the Lambda function macie-trigger to extract the values from the JSON file into a text file. This text file is then uploaded into the same S3 bucket.
The function then checks for other in-progress Amazon Textract jobs in the DynamoDB table. If there are pending jobs, the function exits and waits to be triggered again.
After all of the Amazon Textract jobs are marked as complete in the DynamoDB table, the Lambda function macie-trigger creates a Macie classification job.
Macie then scans the bucket for sensitive data based on managed identifiers and your custom data identifiers.
Macie will continuously publish the classification job status to Amazon CloudWatch Logs.
It might take some time to scan all the files in the S3 bucket, and you will be notified through SNS email when the Macie job is completed. The Lambda function MacieCompletedSNSLambda will filter for completed job status and send an email notification using the SNS topic MacieSnsTopic.
When deploying the solution, you can specify an existing S3 bucket in your AWS account that’s already storing data that might be sensitive or deploy a new S3 bucket as part of the setup. If you specify an existing S3 bucket, make sure that there are no additional statements in the bucket policy or KMS key policy that will deny the relevant solution components access to the S3 bucket. If no existing S3 bucket is specified, a new S3 bucket will be created with the name s3-with-sensitive-data-<account-id>-<random-string>.
Prerequisites
Before deploying the solution, make sure the following prerequisites are in place.
Determine the regular expression (regex) pattern for sensitive textual data that you want Macie to detect. This will allow you to create custom data identifiers that complement the managed data identifiers provided by Macie. For more information, see Building custom data identifiers in Amazon Macie. There’s an example in the pre-deployment steps that you can follow, with the sample images that come with the solution.
Make sure that you have the permissions to deploy the AWS services detailed in the solution: Lambda, Amazon S3, Amazon Textract, Amazon SNS, Macie, Amazon CloudWatch, and DynamoDB.
With the prerequisites in place, you need to set up one or more custom identifiers through the AWS Management Console for Macie before you can deploy the solution. Use the following steps to set up an example custom identifier for the images provided in this post.
Choose Custom data identifiers in the navigation pane, and then choose Create.
Enter a name and description for the custom identifier, such as the following examples:
Name:Singapore NRIC Number
Description:This expression can be used to find or validate a Singapore NRIC Number that begins with the character S, F, T, or G, followed by seven digits and ending with any character from A to Z.
For Regular expression, enter: [SFTG]\d{7}[A-Z].
For Keywords, enter: Singapore,Identity, Card. Keywords are important because they can help to improve the accuracy of the detection and refine the results.
Leave the other fields as default and choose Submit.
Navigate to the newly created custom identifier and note the ID. This ID is required as an input when deploying the AWS SAM solution.
Figure 2: ID of a newly created Macie custom identifier
Deploy the solution
With the prerequisites in place and pre-deployment steps complete, you’re ready to deploy the solution.
To deploy the solution:
Open a CLI window, navigate to your preferred local directory and run git clone https://github.com/aws-samples/enhancing-macie-with-textract.
Navigate to this directory by using cd enhancing-macie-with-textract.
Run sam deploy --guided and follow the step-by-step instructions to indicate the deployment details such as the desired CloudFormation stack name, AWS Region, and other details. The following are descriptions of some of the requested parameters:
ExistingS3BucketName: This is the name of the S3 bucket that you want the solution to scan. This is an optional parameter. If it’s left blank, the solution will create an S3 bucket for you to store the objects that you want to scan.
MacieCustomCustomIdentifierIDList: This is the ID that you noted in the final pre-deployment step. Use this field to enter a list of custom identifiers for Macie to detect with. If there is more than one ID, each ID should be separated by a comma (for example, 59fd2814-0ba8-41cc-adb2-1ffec6a0bb3c, 665cf948-ea30-42df-9f63-9a858cbfe1a8).
EmailAddress: This is the email address that you want Amazon SNS email notifications to be sent to when a Macie job is complete.
MacieLogGroupExists: This checks if you have an existing Macie CloudWatch Log Group (/aws/macie/classificationjobs). If this is your first time running a Macie job, enter No or n. Otherwise, enter Yes or y.
When completed, a confirmation request will be presented for the creation of the required resources. AWS SAM creates a default S3 bucket to store the necessary resources and then proceeds to the deployment prompt. Enter y to deploy and wait for deployment to complete.
After deployment is complete, you should see the following output: Successfully created/updated stack – {StackName} in {AWSRegion}. You can review the resources and stack in the CloudFormation console.
Figure 3: CloudFormation console of the deployed stack
An email will be sent from [email protected] to the email address that you entered in step 3. Choose Confirm subscription to allow SNS to send you Macie job completion emails.
Figure 4: Sample email from Amazon SNS for subscription confirmation
Test the solution
With the solution deployed, use a set of sample images to verify that it can detect sensitive data within images.
To test the solution:
Use the Amazon S3 console to navigate to the bucket you specified during deployment. If you didn’t specify an S3 bucket to scan, look for a new bucket named s3-with-sensitive-data-<account-id>-<random-string>.
In your project directory, there are sample images in sample-images.zip. Unzip the file and upload the sample images into the S3 bucket. The sample images include a US driver’s license, social security card, passport, and a Singapore National Registration Identity Card (NRIC).
Navigate to the AWS Lambda console and select the {StackName}-TextractTriggerLambda-<random-string> function.
Choose the Test tab and then choose Test to start the automated sensitive data discovery process for the uploaded images.
Figure 5: Trigger an Amazon Textract scan on all images in the S3 bucket
The whole process will take about 15 minutes to complete. You will receive an email notification after the Macie scan is completed.
Figure 6: Sample email from Amazon SNS for Macie job completion
Navigate to the Amazon Macie console and select Jobs in the navigation pane. You should see the job Scan for [number of] objects [datetime stamp] that matches the job name shown in the email notification.
In the details panel, choose Show results button and then choose Show findings.
Figure 7: Show Macie data discovery job findings
You will see the findings related to the Macie sensitive data discovery job ID that you selected.
Figure 8: Findings from the data discovery job
Understanding the findings
In this section, we take a closer look at each finding.
In the console, look in the Resources affected column for the finding that ends with singapore-pink-nric-postprocessed.txt and select it. The finding type SensitiveData:S3Object/CustomIdentifier means that the resource contains text that matches the detection criteria of a custom data identifier. The other finding types in this example are from managed data identifiers. See Types of sensitive data findings for more information about Macie finding types.
In the finding information panel, you can also see:
In the Overview section, the resource indicates which resource contains sensitive data. The resource identifies the text file; however, you can identify the original image file because it has the same object name (other than the file type).
In the Custom data identifiers section, you can see the type of sensitive data found. In this case, the finding involves data that matches the regex of a Singapore NRIC.
By using this solution, you can use Macie to detect sensitive data within the images in your S3 bucket and which images each finding corresponds to.
Using the solution
In this post, you have configured a single custom data identifier and a recommended set of managed identifiers. However, you can create and use multiple custom data identifiers in the solution by providing them as a comma-separated list, as mentioned in step 3 of Deploy the solution.
This solution has been designed to enable sensitive data discovery of text in image objects within a single S3 bucket. To expand the scope to include multiple S3 buckets, some additional code and permission changes are required to allow the Lambda functions to process and access multiple existing S3 buckets.
It’s important to note the language capabilities of Amazon Textract. Amazon Textract can extract printed text and handwriting from the standard English alphabet and ASCII symbols. Currently, Amazon Textract supports extraction in English, German, French, Italian, and Portuguese. For more information on what textual information Amazon Textract can identify, see Amazon Textract FAQs.
Clean up the resources
To clean up the resources that you created for this example:
If you didn’t set up the scan on your own S3 bucket, empty the S3 bucket that was created as part of the solution. Open the Amazon S3 console, search for the bucket name s3-with-sensitive-data-<account-id>-<random-string> and choose Empty.
Use one of the following methods to delete the CloudFormation stack:
Use AWS SAM CLI to run sam delete in your terminal. Follow the instructions and enter y when prompted to delete the stack.
Conclusion
In this post, you learned how to enhance the capabilities of Amazon Macie to conduct sensitive data discovery within image files. With this solution, you can extend the benefits of Amazon Macie beyond structured file formats.
If you want to extend the benefits of Amazon Macie to scan your databases for sensitive data, you might find these blog posts useful:
We continue to expand the scope of our assurance programs at Amazon Web Services (AWS) and are pleased to announce the successful completion of our first ever Protected B High Value Assets (PBHVA) assessment with 149 assessed services and features. Completion of this assessment effective October 4, 2024, makes AWS the first cloud service provider (CSP) in Canada to meet this high security bar and provide assurance to our valued customers. This assessment also re-affirms our commitment to helping public and commercial customers achieve and maintain the highest-grade security standard for workloads with increased sensitivity.
What is the PBHVA assessment and why is it important?
The Protected B High Value Asset (PBHVA) overlay seeks to enhance the integrity and availability of customer organizational workloads that are considered to have an increased level of sensitivity. These are systems that the Government of Canada (GC) and its service providers use to support delivery of services at a national scale or that are determined to be significant for handling sensitive information. The overlay is a set of 117 controls from the ITSG-33 security control catalogue (baselined against NIST 800-53), which augments the security safeguards to enhance integrity and availability.
As of October 4, 2024, there are a total of 149 AWS services and features that were assessed by the Canadian Centre for Cyber Security (CCCS) under PBHVA assessment criteria. The assessment covers services and features that are available in both the Canada (Central) and Canada West (Calgary) AWS Regions.
How can you access the assessment?
The summary assessment is available through AWS Artifact. You can also learn more about the PBHVA assessment on our AWS PBHVA webpage.
AWS strives to continuously bring services into scope of its compliance programs to help you meet your architectural and regulatory needs. Please reach out to your AWS account team if you have questions or feedback about the PBHVA assessment.
To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.
If you have feedback about this post, submit comments in the Comments section below.
Amazon Web Services (AWS) is pleased to announce enhancements to our Payment Card Industry (PCI) compliance portfolio, further empowering AWS customers to build and manage secure, compliant payment environments with greater ease and flexibility.
PCI Data Security Standard (DSS): Our latest AWS PCI DSS v4 Attestation of Compliance (AOC) is now available and includes six additional AWS services:
This expansion allows you to use these services while maintaining PCI DSS compliance, enabling innovation without compromising security. You can see the full list of services at AWS Services in Scope by Compliance Program.
AWS CloudHSM: Manage your encryption keys on FIPS 140-2 Level 3 certified hardware in your own virtual private cloud (VPC), with a dedicated, single-tenant hardware security module (HSM) solution.
AWS Payment Cryptography: Use payment HSMs that are PCI PIN Transaction Security (PTS) HSM certified and fully managed by AWS, with PCI PIN and point-to-point encryption (P2PE)–compliant key management.
These refreshed attestations offer you greater flexibility in deploying regulated workloads while significantly reducing your compliance overhead. You can access the PCI DSS and PIN AOC reports through AWS Artifact. This self-service portal provides on-demand access to AWS compliance reports, streamlining your audit processes.
To learn more about our PCI programs and other compliance and security programs, see the AWS Compliance Programs page. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Compliance Support page.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
We continue to expand the scope of our assurance programs at Amazon Web Services (AWS) and are pleased to announce that the Fall 2024 System and Organization Controls (SOC) 1, 2, and 3 reports are now available. The reports cover 183 services over the 12-month period from October 1, 2023 to September 30, 2024, so that customers have a full year of assurance with the reports. These reports demonstrate our continuous commitment to adhere to the heightened expectations for cloud service providers.
Going forward, we will issue SOC reports covering a 12-month period each quarter as follows:
AWS strives to continuously bring services into the scope of its compliance programs to help you meet your architectural and regulatory needs. If you have questions or feedback about SOC compliance, reach out to your AWS account team.
To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.
If you have feedback about this post, submit comments in the Comments section below.
For the second year in a row, Amazon Web Services (AWS) is named as a Leader in the Information Services Group (ISG) Provider Lens Quadrant report for Sovereign Cloud Infrastructure Services (EU), published on December 18, 2024. ISG is a leading global technology research, analyst, and advisory firm that serves as a trusted business partner to more than 900 clients. This ISG report evaluates 19 providers of sovereign cloud infrastructure services in the multi public cloud environment and examines how they address the key challenges that enterprise clients face in the European Union (EU). ISG defines Leaders as providers who represent innovative strength and competitive stability.
ISG rated AWS ahead of other leading cloud providers on both the competitive strength and portfolio attractiveness axes, with the highest score on portfolio attractiveness. Competitive strength was assessed on multiple factors, including degree of awareness, core competencies, and go-to-market strategy. Portfolio attractiveness was assessed on multiple factors, including scope of portfolio, portfolio quality, strategy and vision, and local characteristics.
According to the ISG Provider Lens report, “AWS develops various innovative solutions to meet different sovereignty needs, guided by inputs from regulators, cybersecurity experts, partners and customers. These solutions address factors such as location, workload sensitivity and industry standards.”
Read the report to:
Gather insight on the factors that ISG believes will influence the sovereign cloud landscape in the EU.
Discover why AWS was named as a Leader with the highest score on portfolio attractiveness by ISG.
Learn what makes the AWS Cloud sovereign-by-design and how we continue to offer more control and more choice without compromising on the full power of AWS.
The recognition of AWS as a Leader in this report for the second year in a row is a testament to our efforts to help European customers and partners meet their digital sovereignty and resilience requirements. AWS continues to deliver on the AWS Digital Sovereignty Pledge, our commitment to offering AWS customers the most advanced set of sovereignty controls and features available in the cloud. Earlier this year, we announced plans to invest €7.8 billion in the AWS European Sovereign Cloud by 2040, building on our long-term commitment to Europe and ongoing support of the region’s sovereignty needs. The AWS European Sovereign Cloud, which will be a new, independent cloud for Europe, is set to launch by the end of 2025.
Establishing and maintaining an effective security and governance posture has never been more important for enterprises. This post explains how you, as a security administrator, can use Amazon Web Services (AWS) to enforce resource configurations in a manner that is designed to be secure, scalable, and primarily focused on feature gating.
In this context, feature gating means that newly supported AWS features and configurations can’t be used unless you explicitly approve them. With feature gating, you maintain control over your AWS environment when new services and capabilities are introduced.
This blog post demonstrates a unique approach to giving users, such as DevOps teams, controlled flexibility within safe boundaries by allowing resource provisioning that uses only approved configurations. This approach also accommodates configurations that will be supported in future versions of the resource, keeping them restricted until explicitly approved, as shown in Figure 1.
Figure 1: Restrict resource provisioning to approved configurations only
Apply your resource configuration enforcement
As shown in Figure 2, our solution for resource configuration enforcement (RCFGE) uses AWS CloudFormation Hooks. By using Hooks, you can run custom logic during the provisioning of resources. These are proactive controls because you inspect and enforce resource configurations before the resource is created, updated, or deleted.
Your Hook will only be effective if CloudFormation supports the AWS resources that you are using and if you implement a service control policy (SCP) that helps prevent users from provisioning resources outside of CloudFormation.
Figure 2: How CloudFormation Hooks work
The flow shown in Figure 2 consists of the following five steps:
DevSecOps registers and configures a CloudFormation Hook in the account.
DevOps specifies a CloudFormation template that defines the required resources and configurations.
CloudFormation creates a new stack resource, starting the provisioning process based on the template.
The Hook is triggered before provisioning for each resource that’s defined in the template, and runs custom validation logic.
If the validation checks pass, CloudFormation proceeds with provisioning; if not, the process is terminated.
Make your solution scalable
To achieve scalable operations, you should implement a reusable and generic Hook that targets all supported CloudFormation resource types. This Hook enforces resource configuration by loading resource specification files from an external object storage, such as an Amazon Simple Storage Service (Amazon S3) bucket.
These specification files define validation rules in a declarative language. Using this approach, you can add and remove resource configuration validation rules by editing the declarative files. When you externalize custom logic as decoupled validation rules from the Hook, DevSecOps personnel can manage these rules at scale without affecting your infrastructure.
Figure 3: Externalize custom logic as validation rule files in an S3 bucket
Figure 3 shows how the solution has been revised to support this approach. Steps 1–3 are the same as in the flow shown in Figure 2:
DevSecOps registers and configures a CloudFormation Hook in the account.
DevOps specifies a CloudFormation template that defines the required resources and configurations.
CloudFormation creates a new stack resource, starting the provisioning process based on the template.
The Hook is triggered before provisioning for each resource that’s defined in the template.
The Hook loads the relevant resource specification file from the S3 bucket and executes the validation rules against the current resource in the CloudFormation template.
If the validation checks pass, CloudFormation proceeds with provisioning; if not, the process is terminated.
You need to configure the Hook schema and the Hook configuration schema to evaluate the configurations of all supported resources across your AWS accounts before changes are provisioned. This setup should cover create, update, and delete operations so that the Hook can help prevent non-approved configurations across stacks.
By using AWS CloudFormation Guard, you can externalize validation rules from the Hook, as described in Extend your pre-commit hooks with AWS CloudFormation Guard. Guard is an open source, general purpose, policy-as-code (PaC) evaluation tool that validates CloudFormation templates against custom rules to help you stay aligned with your organizational policies. For example, the CT.S3.PR.1 rule specification demonstrates a Guard rule that requires an S3 bucket to have its settings configured to block public access. These validation rules apply to currently supported AWS resource configurations and features, but they don’t restrict potential future properties.
Boost your solution with feature gating
Your risk model might lead you to look for mechanisms that further restrict the AWS resource configurations that you allow in your environments. As you will see, the proposed solution restricts authorized workforce users so that they can use new configurations only if you enable them. The proposed approach uses feature gating because it continues to enforce your configurations even when AWS adds new options for your resources.
Guard aims to validate required constraints; but to meet the feature gating objective, you should implement validation rules that check whether resource configurations fulfill structural constraints described by the restricted version of CloudFormation resource schemas. These schemas help you confine the possible resource configurations that can be provisioned in your environment no matter what new configurations AWS introduces.
Figure 4: Enforce resource configuration with restricted resource schema templates
Figure 4 shows an updated version of the same flow where validation rules are implemented by using restricted resource schema templates, which are stored in an S3 bucket. These templates are based on the original CloudFormation resource schemas, representing a snapshot of these schemas at a specific point in time. Steps 1–4 are the same as in the flow shown in Figure 3:
DevSecOps registers and configures a CloudFormation Hook in the account.
DevOps specifies a CloudFormation template that defines the required resources and configurations.
CloudFormation creates a new stack resource, starting the provisioning process based on the template.
The Hook is triggered before provisioning for each resource that’s defined in the template.
The Hook loads the relevant restricted resource schema template file from the S3 bucket and uses it to execute schema validation against the current resource in the CloudFormation template.
If the validation checks pass, CloudFormation proceeds with provisioning; if not, the process is terminated.
A restricted resource schema template is a subset of its corresponding original CloudFormation resource schema. It includes additional constraints that limit certain properties to specific values and patterns or exclude certain properties entirely. Furthermore, these templates contain placeholders that you fill in with runtime values, such as the account ID, which your Hook provides as part of the Hook context.
As shown in Figure 5, the flow within the RCFGE CloudFormation Hook involves the following steps:
The CloudFormation Hook is invoked with the Hook context and the resource’s configuration JSON object.
The Hook loads the restricted resource schema template from the S3 bucket and substitutes placeholders with the Hook context runtime values, producing a valid JSON schema.
The Hook validates the stack’s resource configuration JSON object against the schema. If it returns OperationStatus.SUCCESS, then CloudFormation proceeds with the provisioning process. If it returns OperationStatus.FAILED, then CloudFormation terminates the provisioning process.
If a restricted resource schema template for a CloudFormation resource type isn’t found in the S3 bucket, the schema validation step fails by default.
Sample excerpt of a restricted schema template for an S3 bucket resource
The following is an excerpt from a restricted schema template for an S3 bucket. At runtime, your Hook processes this template, substituting the placeholders with relevant values from the Hook context. In this example, the Hook replaces the <accountID> placeholder in the topic’s pattern with the actual account ID. The resulting JSON schema disallows additional properties beyond those defined by the schema and restricts the Amazon Simple Notification Service (Amazon SNS) topics that can be used for event notifications.
Note: In the code samples that follow, we’ve omitted some code for brevity—we’ve indicated these omissions with three periods: ...
CloudFormation template for an S3 bucket that adheres to the restricted schema
Let’s assume that your account ID is 111122223333. The account ID is propagated to the Hook through the Hook context.
The following is an excerpt from a CloudFormation template that aligns with the restricted schema for an S3 bucket instantiated from the template shown previously. As a result, your Hook allows the corresponding CloudFormation stack to proceed.
CloudFormation template for an S3 bucket that diverges from the restricted schema (example 1)
The following is an excerpt from a CloudFormation template that doesn’t align with the restricted schema for an S3 bucket instantiated from the template shown previously because it attempts to configure the Amazon SNS topic for the notification configuration, which uses an Amazon Resource Name (ARN) of another account. As a result, your Hook causes the corresponding CloudFormation stack to fail.
CloudFormation template for an S3 bucket that diverges from the restricted schema (example 2)
The following is an excerpt from a CloudFormation template that doesn’t align with the restricted schema for an S3 bucket instantiated from the template shown previously. This time, it violates your feature gating objective by attempting to use a new, imaginary feature of an S3 bucket that isn’t approved for use by your restricted schema for an S3 bucket. As a result, your Hook causes the corresponding CloudFormation stack to fail.
If a security control itself isn’t protected adequately, it becomes a weak link in the security chain. For example, a surveillance camera (a physical security control) that isn’t securely mounted can be removed, rendering it useless. This principle also applies to your RCFGE solution.
Next, we will show you how to isolate management activities to a dedicated account and use SCPs as preventative controls.
Isolate RCFGE management in a dedicated account
Organizing your AWS environment by using multiple accounts is a best practice because it enhances security, simplifies management, and allows for better resource isolation and cost tracking. Isolating the operation and management of your RCFGE solution in its own dedicated account is essential for securing the solution’s resources.
With AWS CloudFormation StackSets, you can deploy and manage RCFGE stacks across multiple accounts and AWS Regions from a single central administrator account. This provides consistent and scalable infrastructure while maintaining centralized governance. With this functionality, you can deploy the RCFGE resources to existing accounts and automatically include new accounts as you add them to your organization, simplifying RCFGE management and providing uniformity across your environments. For more information, see Deploy CloudFormation Hooks to an Organization with service-managed StackSets.
Figure 6 shows how to extend that idea so that you can operate the RCFGE solution at scale while maintaining isolation and the separation of duties. The solution operates across three key account types:
Management account –use this account to create your organization and designate the CloudFormation StackSets delegated administrator account.
Delegated administrator account – this account serves as the centralized management point for the RCFGE solution. It contains a continuous integration and continuous delivery (CI/CD) pipeline that provisions RCFGE resources across the organization by using CloudFormation StackSets with service managed permissions. The account hosts a centralized S3 bucket that stores the RCFGE restricted resource schema templates. The security engineering team uses this account to submit Hook code and restricted resource schema template changes, which trigger the CI/CD pipeline.
Member accounts – each member account contains an RCFGE StackSet instance and an AWS Identity and Access Management (IAM) role for provisioning RCFGE resources. It also includes a CloudFormation Hook and an IAM role that allows the Hook to access the centralized S3 bucket with RCFGE restricted resource schema templates.
Figure 6: Securely operate the RCFGE solution
Let’s explore how the RCFGE solution architecture enforces resource configuration step by step, as shown in Figure 7.
Figure 7: CloudFormation stack deployment flow with RCFGE validation and enforcement
DevOps initiates the deployment by specifying a CloudFormation template that defines the resources and configurations needed.
CloudFormation creates a new stack resource, initiating the resource provisioning process based on the provided template.
The RCFGE CloudFormation Hook is triggered for each resource defined in the CloudFormation template.
The Hook loads the corresponding restricted resource schema template from the S3 bucket.
The Hook validates a resource configuration:
The Hook processes the restricted resource schema template to create a JSON schema.
It uses this JSON schema to validate the current resource in the CloudFormation template.
If the resource is invalid according to the schema, the provisioning process is terminated.
If the current resource passes validation, CloudFormation proceeds with the resource provisioning process by creating and configuring the resources as specified in the template.
Use SCPs as preventive controls for your organization to help protect RCFGE
The following SCP excerpt accomplishes three objectives:
Implements a statement (see AllowedListActions) to explicitly specify the access that is allowed while other access is implicitly blocked.
Implements control objectives to help prevent changes to resources set up by the RCFGE solution (see ProtectRCFGEResources and ProtectStackSetExecutionRole).
Makes sure that AWS resource provisioning does not occur outside of CloudFormation (see ProvisionResourcesViaCloudFormationOnly).
In this SCP excerpt, the ProvisionResourcesViaCloudFormationOnly statement restricts CloudFormation stacks to being managed only through forward access sessions (FAS) in AWS IAM.
The ProvisionResourcesViaCloudFormationOnly statement explicitly prohibits direct create, update, and delete actions for all supported resources used in your environment. If needed, split this statement into multiple parts so you don’t exceed SCP size limits, while providing comprehensive coverage of your resources to make sure that they are provisioned and managed only through CloudFormation.
The ProtectStackSetExecutionRole statement in this example assumes that CloudFormation trusted access is activated with AWS Organizations, which is required by StackSets to deploy across accounts and Regions by using service managed permissions.
To allow the Hook to retrieve the necessary restricted resource schema templates, member accounts must be able to access the S3 bucket that contains the RCFGE templates. The following code sample shows the bucket policy for the S3 bucket that contains the RCFGE templates.
As shown in the following code sample, the RCFGEHookExecutionRole IAM role in member accounts has a policy that grants read-only access to the RCFGE templates that are stored in an S3 bucket in the RCFGE delegated administrator account, where 555555555555 represents the account ID.
In the following code sample, the RCFGEHookExecutionRole IAM role in member accounts has a trust policy that allows it to be assumed only by the relevant CloudFormation service principals, where 444455556666 represents the account ID of the member account.
Define baseline configuration for RCFGE and continuous monitoring with AWS Config
Defense in depth is an effective strategy because if one line of defense fails, additional layers are in place to help stop threats at subsequent points. With AWS Config, you can capture the configuration of RCFGE resources over time. You can set up AWS Config custom rules to automatically assess the compliance of your RCFGE resources against predefined policies. For example, you can use an AWS Config custom rule to make sure that the RCFGE Hook hasn’t been altered or removed.
Conclusion
In this post, you learned how to use CloudFormation Hooks to create a resource configuration enforcement (RCFGE) solution on AWS that is designed to be secure and scalable and that supports feature gating. Using this approach, you, as a security administrator, can maintain strict control over resource configurations and feature adoption across your AWS environments. The solution provides a balanced approach to governance, so that DevOps teams have the flexibility to work within approved boundaries while making sure that new AWS features are only accessible after explicit approval.
If you have feedback about this post, submit comments in the Comments section. For questions, start a new thread on the CloudFormation re:Post or contact AWS Support.
As organizations continue their cloud journeys, effective data security in the cloud is a top priority. Whether it’s protecting customer information, intellectual property, or compliance-mandated data, encryption serves as a fundamental security control. This is where AWS Key Management Service (AWS KMS) steps in, offering a robust foundation for encryption key management on AWS.
One of the first questions that often arises for customers is, “How many keys do I actually need?” This seemingly simple question requires careful consideration of various factors. Although AWS KMS makes encryption straightforward, organizations need to consider several aspects of their key management strategy. These include choosing between AWS managed keys, customer managed keys, and importing your own keys (BYOK), as well as deciding between centralized and decentralized key management approaches. Each option has its own benefits and trade-offs in terms of security, control, and operational overhead. By understanding these choices and how they align with your organization’s needs, you can develop an effective and efficient key management strategy.
In this blog post, we explore the main considerations that drive your AWS KMS key strategy, from organizational structure to compliance requirements. Should you maintain a centralized key management approach with a single team controlling all keys, or adopt a decentralized model where individual teams manage their own keys? These decisions are important because they relate to the AWS shared responsibility model, where AWS maintains the security of the cloud, while customers remain responsible for security in the cloud, including the proper management and use of encryption keys.
Overview – What is AWS Key Management Service?
AWS Key Management Service (AWS KMS) is an AWS managed service that makes it convenient for you to create and control the encryption keys that are used to encrypt your data. The keys that you create in AWS KMS are protected by FIPS 140 Level 3 validated hardware security modules (HSM). The keys never leave AWS KMS unencrypted. To use or manage your KMS keys, you interact with AWS KMS.
Customers are responsible for deciding what data to encrypt, choosing the appropriate encryption keys, and implementing encryption across AWS services with the help of the key policy. Customers are responsible for monitoring and auditing the use of encryption keys through services such as AWS CloudTrail.
A critical aspect of customer responsibility is determining how to manage the keys and how many KMS keys are needed. This decision depends on various factors such as data classification, application architecture, regulatory requirements, and operational needs. We look at these areas in more detail in the next sections.
Guiding principles for key strategy
Following are four guiding engineering principles that, based on our experience, help create a secure and easier-to-maintain system. They will assist you in determining the approximate number of KMS keys for your organization based on your management requirements.
Principle 1 – Data Classification: If a system processes data of different classification levels, employ separate data resources and separate KMS keys to separately govern and audit access to the data. With similarly classified data or a single type of data, the usage of just one KMS key may be justified.
Why it matters: This principle helps to ensure that data that is classified into different sensitivity levels is protected appropriately based on access to encryption keys for that same classification, reducing the risk of unauthorized access and simplifying governance.
Principle 2 – Applications: Multiple applications can run in one AWS account. We recommend that you use distinct KMS keys for each application, because managing access to an individual key can become a complex task when it is delegated to two or more application administrators. Use separate KMS keys for applications running in distinct AWS accounts to further make use of the account boundary, limiting the potential impact in case of a security incident. Use separate keys for distinct application stages (such as development, staging, or production).
Why it matters: This approach isolates access to applications and application access to data. This reduces the potential impact of unintended access to a key.
Principle 3 – AWS Services: When you consider key management across multiple AWS services, focus on both the services and the nature of the data. If you are dealing with one type of data (for example, customer information) that flows through multiple AWS services as part of one application or workflow, consider using a single KMS key. This simplifies key management while maintaining consistent access control. For instance, a customer record that is stored in Amazon Simple Storage Service (Amazon S3), processed by AWS Lambda, and then stored in Amazon DynamoDB could use the same KMS key across these services as mentioned in Principle 1.
However, if you are handling different types of data (such as financial records and user preferences) across various AWS services, even within the same application, consider using separate KMS keys on a per-service basis. This allows for more granular access control and adheres to the principle of least privilege. For example, in an e-commerce application, you might use one KMS key for encrypting payment information in Amazon Relational Database Service (Amazon RDS) and a different key for encrypting user browsing history in Amazon Redshift.
The decision to use one key or multiple keys should be based on your data classification policies and access control requirements. With this approach, you can keep your key management strategy aligned with your data governance policies, regardless of which AWS services you are using.
Why it matters: This principle balances the need for simplicity with the requirement for granular control over data access across different AWS services.
Principle 4 – Separation of Duties: Key policies define who can administer and who can use the key. In the case of distinct encryption use cases and distinct administrators, we recommend that you create separate KMS keys. Another aspect of separation of duties is that, with KMS key policies, two different principals can be made responsible for governing data and data decryption access. However, this does not influence the count of keys.
Why it matters: This principle supports the implementation of least privilege access and helps maintain clear accountability in key management.
By applying these principles, you can develop a key management strategy that describes how many KMS keys you may need, and that balances security, compliance, and operational efficiency. In the following sections, we explore how to apply these principles in various scenarios.
Examples of key management strategy and comparison of centralized and decentralized approaches
In addition to the guiding principles discussed earlier, the structure of your organization and its specific needs play a crucial role in determining the most suitable approach to key management. When implementing key management strategies, organizations generally choose from three main approaches: centralized, decentralized, or a hybrid model. The choice depends on the organization’s structure, needs, and operational context. Each approach offers distinct advantages for specific organizational scenarios.
A decentralized approach is our recommended approach, as most customers fit into the following scenarios:
Organizations with autonomous business units or where governance controls provide oversight of key usage
Companies where development teams are agile and ownership of keys can be centrally audited
Companies that operate in multiple regulatory frameworks
Companies that require to operate in a particular AWS Region
A centralized KMS approach is best suited for the following scenarios:
Organizations that require strict compliance oversight and centralized management
Companies with centralized security or data protection functions
In a hybrid model, there is a blend between centralized and decentralized:
Core key policies are managed centrally
Day-to-day key operations are handled by teams
For example, organizations or companies could have independent product teams, but a centralized security team.
Example 1 (Hybrid): A retail website with public product catalog data and confidential customer data should use two KMS keys—one for the public catalog that is encrypted in Amazon S3, and one for customer data that is encrypted in Amazon RDS and other AWS services.
Rationale: This recommendation is based primarily on Principle 1 (Data Classification). The public catalog data and confidential customer data represent different classification levels, justifying the use of separate keys. This approach is further supported by Principle 3 (AWS Services), because the data resides in different AWS services and is of a varied nature.
The benefits of this approach:
Implement appropriate access controls for each data type
Manage encryption independently for each data classification
Enhance overall data security and compliance
Example 2 (Decentralized): A healthcare company with several application teams could use a separate KMS key for each application team, with distinct key policies for each key based on the data and roles of each team.
Rationale: This recommendation is primarily based on Principle 2 (Applications). With multiple application teams operating within the healthcare company, each potentially dealing with distinct types of data and having different access requirements, separate KMS keys provide for independent management of encryption and access for each team. This approach is further supported by Principle 4 (Separation of Duties), allowing for team-specific key policies.
The benefits of this approach:
Maintain granular control over data access.
Implement team-specific encryption policies.
Uphold the principle of least privilege across the organization.
Enhance data security: By using separate keys, the company limits the impact of improper access to any given key, enables more precise access control, facilitates independent key rotation schedules, and improves the ability to monitor and audit key usage for each application.
Simplify alignment with healthcare regulations: Separate keys support data segregation requirements, enable fine-grained role-based access control, provide clear audit trails for each application’s data access, and allow for tailored data lifecycle management. This functionality is crucial for aligning with various healthcare compliance standards such as HIPAA.
Allow for efficient and distributed key management that is tailored to each application team’s needs.
These examples demonstrate how applying the guiding principles can lead to a well-structured key management strategy, tailored to the specific needs of different organizations and use cases.
Considerations for key management
When you implement your key management strategy, several factors need to be considered beyond just the number of keys. This section explores these considerations to help you make informed decisions about your key management approach.
Key types
AWS offers different types of KMS keys, each with its own benefits and use cases.
AWS owned keys are managed by AWS in service accounts, used across multiple customer accounts, and provide no customer visibility or audit capability. Choose AWS owned keys when there are no management or audit requirements for the keys, but encryption of the data at rest is needed.
AWS managed keys are managed entirely by AWS and are used only for your AWS account. Although customers can view these keys in the AWS Management Console and track their usage in AWS CloudTrail logs, they have limited ability to directly control or modify these keys. Choose AWS managed keys when managing keys is not a requirement, but having an audit trail is. It’s worth noting that AWS managed keys are automatically rotated every year, which can be convenient for many use cases.
Customer-managed keys offer the highest level of control and customization, allowing creation of key policies and control over key rotation. However, customer managed keys provide more flexibility, allowing you to set your own rotation schedule or even enable rotation if you are required to do so for regulatory reasons. Choose customer managed keys when you need strict control over key usage and the ability to share keys or control access through key policies, detailed auditing capabilities, alignment with specific compliance requirements, or the ability to integrate key management with your existing processes and tools.
The decision between AWS managed and customer managed keys often comes down to balancing the convenience of automatic management with the need for granular control and customization. As the number of keys increases, so does the complexity of management. More keys mean more policies to create, manage, and audit. Making sure that the right people have access to the right keys becomes more challenging. However, to help audit KMS key access, you can use the IAM Access Analyzer to determine external access to your keys. Managing rotation schedules for multiple keys requires more effort, and more keys mean more policies to analyze and monitor, as well as growing costs.
Cost
Security should be the primary concern, but cost is also a factor. Each customer managed key incurs a monthly storage cost. Both AWS managed and customer managed KMS keys have API usage costs associated with them. Key rotation can increase costs over time, as old key versions are retained.
Manageability
Finding the right balance between security and manageability is crucial. Too few keys might not provide adequate separation of duties or granular access control, while too many keys can lead to increased complexity, higher costs, and potential mismanagement.
Specific requirements
Different industries and regions may have specific requirements for key management. Some regulations might require separation of duties, necessitating multiple keys. Certain compliance standards might dictate specific key rotation or audit trail requirements.
By carefully considering these factors alongside the guiding principles discussed earlier, you can develop a key management strategy that balances security, compliance, cost-effectiveness, and operational efficiency for your specific needs. It is important to approach your KMS strategy holistically, considering not just your immediate security needs, but also the long-term management implications. Regular review and adjustment of your key management strategy will provide assurance that it continues to meet your evolving needs while maintaining robust security and compliance.
Conclusion
As we explored throughout this post, determining the optimal number of AWS KMS keys for your organization is a nuanced decision that balances security, compliance, cost, and operational efficiency. The guiding principles we discussed—data classification, application segregation, AWS service integration, and separation of duties—provide a solid framework for making these decisions. Remember that there’s no one-size-fits-all solution; the right approach depends on your specific needs and circumstances.
As you move forward in implementing or refining your KMS key strategy, consider these next steps: First, conduct a thorough audit of your current data assets, their classifications, and the applications and services that interact with them. Next, map out your ideal key management structure based on the principles we’ve discussed. Then, evaluate the costs and operational overhead of your proposed strategy, adjusting as necessary to find the right balance for your organization. Finally, implement your strategy incrementally, starting with your most sensitive or critical data assets.
Remember that key management is an ongoing process. Regularly review and update your strategy as your data landscape evolves, new compliance requirements emerge, or AWS introduces new features. By thoughtfully applying the principles and considerations we’ve discussed, you can create a robust, scalable, and efficient key management strategy that helps your overall security posture and meets your organization’s unique needs.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
As organizations increasingly use generative AI to streamline processes, enhance efficiency, and gain a competitive edge in today’s fast-paced business environment, they seek mechanisms for measuring and monitoring their use of AI services.
To help you navigate the process of adopting generative AI technologies and proactively measure your generative AI implementation, AWS developed the AWS Audit Manager generative AI best practices framework. This framework provides a structured approach to evaluating and adopting generative AI technologies and addresses important aspects such as strategy alignment, governance, risk assessment, and security and operational best practices. You can use the framework within AWS Audit Manager as you implement generative AI workloads, to measure and monitor existing workloads through Audit Manager capabilities such as automated evidence collection and customized assessment reports.
In this blog post, we’ll cover the AWS Audit Manager generative AI best practices framework and how it can help you during your generative AI journey. We’ll highlight key considerations to prioritize when deploying generative AI workloads, and discuss how the framework can facilitate auditing and compliance with generative AI-specific controls using Audit Manager.
Starting the generative AI Journey
An important consideration in preparing for the introduction of generative AI in your organization is the need to align your risk management strategies with robust mitigation measures. Examples of potential risks include the following:
Data quality, reliability, and bias: Poor source-data quality used to train models might lead to inconsistent, inaccurate, or biased outputs, which can have significant financial and regulatory impact for organizations. For example, a language model trained on biased data might generate text that reinforces harmful stereotypes or propagates misinformation. Similarly, training AI on biased product reviews or ratings might lead to product suggestions that don’t accurately reflect product quality or user preferences.
Model explainability and transparency: The opaque nature of many generative AI models makes it challenging to understand how they arrive at specific outputs or decisions. For example, if a model is used to generate creative content, such as stories or learning materials, it could be difficult to understand why certain outputs are generated, including potential biases or inappropriate content.
Data privacy and security: Generative AI models are trained on vast amounts of data, which might inadvertently include sensitive or personal information. For example, a model trained to generate text could potentially produce sentences that contain personal details from its training data.
AWS empowers organizations to use this technology responsibly while helping them to align with best practices. As part of enabling organizations to create a comprehensive risk management strategy for generative AI systems, AWS has built the AWS Audit Manager generative AI best practices framework which is mapped to Amazon Bedrock and Amazon SageMaker in AWS Audit Manager.
Amazon Bedrock is a managed service that enables you to create, manage, and scale machine learning (ML) and AI services while facilitating adherence to security and defined compliance requirements. Amazon SageMaker is a fully managed ML service that can build, train, and deploy ML models for extended use cases that require deep customization and model fine-tuning.
You can use this framework to facilitate your auditing and compliance requirements by taking advantage of controls for more responsible, ethical, and effective deployment of generative AI models.
The framework is organized into four pillars, as follows:
Data Governance: Data is the foundation of generative AI models, and the quality and diversity of the training data can significantly impact the model’s performance and output. The Data Governance pillar focuses on facilitating data management practices such as data sourcing, data quality, data privacy, and data bias.
Model Development: This pillar focuses on the responsible development and testing of generative AI models and covers aspects such as model architecture selection, model training, and model evaluation.
Model Deployment: This pillar addresses the challenges associated with deploying generative AI models in production environments and covers aspects such as model deployment strategies, infrastructure considerations, and access controls.
Monitoring & Oversight: This pillar focuses on the ongoing monitoring and governance of generative AI models in production environments and addresses aspects such as model performance monitoring and incident response planning.
You can also use Amazon Bedrock Guardrails to provide an additional level of control on top of the protections built into foundation models (FMs) to help deliver relevant and safe user experiences that align with your organization’s policies and principles.
Each organization’s generative AI journey is unique, influenced by factors such as industry-specific regulations, risk appetite, and scale of generative AI deployment. By integrating the framework with Amazon Bedrock or Amazon SageMaker, you can customize the controls to your organization’s unique needs, aligning your generative AI deployments with your specific risk management strategies. This customization is especially valuable for highly regulated sectors, such as the financial sector.
For example, you can map the risk of inaccurate outputs to controls related to data quality and model validation. Similarly, you can map data security risks to controls related to access management and encryption.
Let’s consider an example that uses a subset of these risks to understand how you could perform this mapping. A financial services firm decides to use generative AI models to develop a chatbot capable of understanding complex customer inquiries and providing accurate and tailored responses for their customer portal. Although chatbots can greatly enhance customer experiences and operational efficiency, they also introduce risks that you need to understand and measure, so that you can develop a corresponding mitigation strategy.
An auditor within the internal audit function of the financial organization would like to use the AWS Audit Manager generative AI best practices framework to assess compliance with the following sample of risks associated with the application:
Responsible: Validating that the chatbot adheres to ethical principles, such as fairness and transparency, and avoids perpetuating biases or discrimination against certain customer segments.
Accurate: Verifying the reliability and accuracy of the chatbot’s responses, particularly when handling sensitive financial information or providing advice on complex financial products.
Secure: Protecting the integrity and security of the data being used to train the generative AI model from unauthorized access and validating that sensitive customer data is segregated from data used for training.
Example mapping
We’ve provided an example mapping here that illustrates how you can use the framework within Audit Manager to develop a risk management strategy. Based on your individual control objectives and organizational requirements, you can further customize controls, and evidence collection can be automated or manually defined. The example mapping is as follows:
Responsible: Implement mechanisms for AI model monitoring and explainability to detect and mitigate potential biases or unfair outcomes.
RESPAI3.8: Document Risks and Tolerances: Define, document, and implement specific controls to address identified risks and organizational risk tolerances.
RESPAI3.9: Develop AI RACI: Define organizational roles and responsibilities, lines of communication, and ownership of controls to address identified risks. Ensure that this mapping, measuring, and managing of generative AI risks is clear to individuals and teams throughout the organization.
RESPAI3.13: Continuous Risk Monitoring: Periodically perform retrospectives and review policies and procedures to determine if new risks should be considered, and if current risks are addressed based on AI performance, incidents, and user feedback.
RESPAI3.15: Ethical Guidelines: Develop and adhere to ethical guidelines for the deployment and usage of generative AI models.
Accurate: Implement robust data quality checks, model validation processes, and ongoing monitoring to ensure the accuracy and reliability of the generative AI chatbot’s outputs.
ACCUAI3.4: Regular Audits: Conduct periodic reviews to assess the model’s accuracy over time, especially after system updates or when integrating new data sources.
ACCUAI3.6: Source Verification: Ensure that the data source is reputable, reliable, and the data is of high quality.
ACCUAI3.14: Quality Data Sourcing: The accuracy of generative AI largely depends on the quality of its training data. Ensure that the data is representative, comprehensive, and free from biases or errors.
Secure: Implement robust access controls, data encryption, and security monitoring measures to protect the generative AI chatbot system and training data.
SECAI3.2: Data Encryption In Transit: Implement end-to-end encryption for the input and output data of the AI models to minimum industry standards.
SECAI3.3: Data Encryption At Rest: Implement data encryption at rest for data that’s stored to train the AI models, and for the metadata that’s produced by AI models.
Note: This is an example of a control that can be configured with automated evidence collection using AWS Config as the underlying data source, or further customized with additional data sources according to the scope of the control.
SECAI3.7: Least Privilege: Document, implement, and enforce least privileged principles when granting access to generative AI systems.
SECAI3.8: Periodic Reviews: Document, implement, and enforce periodic reviews of users’ access to generative AI systems.
Note: This is an example of a control that can be configured with manual evidence collection based on the specific policies and procedures defined by each organization.
SECAI3.15: Access Logging: Require and enable mechanisms that allow users to request access to generative AI models. Ensure that access requests are properly logged, reviewed, and approved.
Conclusion
It’s important for institutions, especially those in highly regulated sectors, to proactively address new developments that relate to generative AI. Using the AWS Audit Manager generative AI best practices framework as part of a comprehensive risk management strategy can help you stay ahead of the curve and embrace an agile and responsible approach to generative AI.
The guidance provided by the framework, together with the capabilities of Audit Manager, Amazon Bedrock and SageMaker can help you establish secure and controlled environments for generative AI implementation, automate evidence collection and risk assessments, and monitor and mitigate potential risks. By embracing the potential of generative AI while adhering to best practices, you can position your organization at the forefront of innovation while maintaining the trust and confidence of stakeholders and customers.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Amazon CloudWatch dashboards are customizable pages in the CloudWatch console that you can use to monitor your resources in a single view. This post focuses on deploying a CloudWatch dashboard that you can use to create a customizable monitoring solution for your AWS Network Firewall firewall. It’s designed to provide deeper insights into your firewall’s performance and security events simplifying security monitoring.
Network Firewall is a managed service that you can use to deploy essential network protections to Amazon Virtual Private Clouds (Amazon VPCs). Network Firewall provides comprehensive logs and metrics through CloudWatch, and we’re expanding its capabilities with this CloudWatch dashboard. This enhancement makes it easier to visualize, analyze, and act on the wealth of data generated by your firewall.
This open source solution streamlines network security monitoring with a user-friendly AWS CloudFormation template that quickly deploys a dedicated monitoring dashboard. This solution incorporates a suite of CloudWatch features—basic monitoring metrics, vended logs, Logs Insights queries, Contributor Insights rules, and the dashboard itself—into a centralized view. Preconfigured widgets provide instant insights into critical areas such as top talkers, protocol distributions, and alert log trends, in addition to HTTP and TLS flow analysis. A consolidated view of key metrics and logs enables faster identification of potential security threats or performance issues. With all of this relevant network firewall data in one place, your team can respond more quickly to emerging security events.
In this blog post, we provide an overview of the dashboard and a step-by-step guide to deploy it in your environment.
Solution overview
The CloudWatch dashboard can be deployed in all AWS Regions where Network Firewall is available today, including the AWS GovCloud (US) Regions and China Regions. While the dashboard comes pre-configured, you can quickly adjust queries, time ranges, and refresh intervals to help meet your specific needs. By default, the dashboard queries firewall flow and alert log events over a 3-hour period, impacting the number of log events scanned. Logs Insights and Contributor Insights widgets showcase the top 10 data points by default, but you can enhance results by modifying queries or adjusting the Top Contributors value, though this might lead to increased costs. You can configure the auto-refresh interval of the widgets to get real-time visibility and optimize costs. See the Amazon CloudWatch Pricing guide for up-to-date free and paid tier pricing considerations.
The dashboard, shown in Figure 1, can be deployed using CloudFormation and includes data and analytics from the following sources:
Native CloudWatch metrics from the AWS/NetworkFirewall and AWS/PrivateLinkEndpoints namespaces
CloudWatch Logs Insights queries that analyze Network Firewall flow and alert logs
CloudWatch Contributor Insights rules that aggregate data from Network Firewall flow and alert logs.
Figure 1: CloudWatch dashboard
Walkthrough
In the dashboard, the Logs Insights and Contributor Insights widgets display the top 10 data points by default. You can edit the Insights queries or change the Top Contributors to a larger value to display more results, as shown in Figure 2.
Figure 2: Top Talkers dashboard showing a change to the Top Contributors value
You can also manually refresh the data within a single or multiple widgets, or you can configure the entire dashboard to automatically refresh at a configured time interval as shown in Figure 3. The dashboard won’t automatically refresh the widget data by default.
Figure 3: Configuring the dashboard to automatically refresh
Prerequisites
Deploying the Network Firewall CloudWatch Dashboard is straightforward. You will need the following:
A Network Firewall in your VPC.
Your Network Firewall must be configured to publish firewall flow and alert logs to two different CloudWatch log groups. For example, firewall flow logs are published to /my-firewall-flow-logs and alert logs are published to /my-firewall-alert-logs.
If you haven’t deployed Network Firewall in your VPC, you can use one of the available AWS Network Firewall Deployment Architecture templates to create a firewall. After creating a firewall, configure CloudWatch log groups for the firewall flow and alert logs and configure stateful logging as described previously. Fine-tune your firewall policy and rule configuration and make sure that you’re routing traffic symmetrically through the firewall. With the firewall now in the routed path and publishing metrics and log events, you can proceed with this Network Firewall CloudWatch dashboard template.
Deployment
The Network Firewall dashboard CloudFormation template creates a monitoring dashboard for a single Network Firewall firewall. Make sure that you launch this CloudFormation stack in the same AWS Region and account as the firewall, regardless of whether the firewall is set up centrally or in a distributed manner.
To deploy the dashboard:
Choose Launch Stack for the relevant AWS Region. Make sure that you’re signed in to the appropriate AWS account and Region.
Region: China
Region: Gov Cloud
Region: All other regions supported by AWS Network Firewall
You will be redirected to the Create stack page in the AWS Management Console for CloudFormation. Make sure that you’re in the correct Region and using the correct template. Choose Next. The following are the Regions and their template names:
Figure 4: Make sure that you’re using the correct template
When launching the stack, you will need to enter the following parameters:
Stack name: A descriptive name for this CloudFormation stack. For example, my-firewall-dashboard.
Firewall name: The firewall name as seen in the Amazon VPC console. In the Amazon VPC console, choose Network Firewall in the navigation pane, then choose Firewalls.
Firewall subnets: The firewall subnet IDs to which your firewall endpoints are attached. The firewall subnets can be found on the Firewall details tab of your firewall in the Amazon VPC
Flow log group name: The name of the CloudWatch log group where your firewall flow logs are stored.
Alert log group name: The name of the CloudWatch log group where your firewall alert logs are stored.
Contributor Insights rule state: Enable or disable the Contributor Insights rules (the template defaults to enabled). Disabling will stop the rules from scanning log data and displaying results in the Contributor Insights widgets. After the rules are created, you can change the state of one or more Contributor Insights rules from CloudWatch console by choosing Insights from the navigation pane, and then choosing Contributor Insights.
After the stack reaches CREATE_COMPLETE status, go to the Outputs tab and choose the FirewallDashboardURI link to open the new dashboard in the CloudWatch Dashboards console. It might take a few minutes for the Logs Insights and Contributor Insights widgets to start displaying data. For more details about each widget, see the README. If you don’t have log events matching the query parameters in the widgets, some widgets might not show data points.
Troubleshooting
If you encounter issues during or after deployment, review the following:
Both firewall flow and alert logging are enabled, not just one.
Log group names are entered correctly; incorrect names will cause widgets to point to invalid data.
Correct subnets are selected. Incorrect choices can impact the PrivateLink metrics widgets.
Firewall name is entered correctly. An incorrect name can disrupt metrics widgets, dashboard, and Contributor Insights widget names and break the firewall link.
Cleaning up
You can delete the Network Firewall CloudWatch dashboard and all of the associated resources with a few clicks. Deleting the dashboard will not impact the routing and network traffic inspection performed by the firewall.
Sign in to the CloudFormation console in the Region where you launched the stack and choose Stacks from the navigation pane.
Select the Stack name you chose when launching the stack. For example, my-firewall-dashboard.
Choose Delete.
Conclusion
We encourage you to see for yourself how this new dashboard can enhance your network security management. To get started with the AWS Network Firewall CloudWatch Dashboard, visit our GitHub repository for detailed instructions and the CloudFormation template. For a visual overview of the dashboard and its capabilities, check out our YouTube video.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
According to a 2024 Verizon report, nearly 70% of data breaches occurred because a person was manipulated by social engineering or made some type of error. This highlights the importance of human-layer defenses in an organization’s security strategy. In addition to technology, tools, and processes, security requires awareness and action from everyone in an organization to recognize anomalies, escalate potential issues, and ultimately, mitigate risk.
Organizations that invest in a culture of security see better employee adoption of security controls, improved cybersecurity behavior, and a more effective use of cybersecurity resources, according to a 2024 Gartner analysis. This aligns with our own experience at AWS, where we deeply invest in our culture of security. Our leadership prioritizes security and builds it into our organizational structure. Everyone, regardless of role, views security as a shared responsibility. Security advocates and advisors are embedded in our teams to share their expertise, and innovation empowers our people to move fast while staying secure.
Building and maintaining a culture of security requires constant investment and focus. In our recent culture of security series with The Guardian, we share perspectives from AWS leaders on some of the most common questions that people ask us about how to create a culture of security:
The journey to creating a culture of security begins with the first step. Although this journey looks different for every organization, sharing what we’ve learned may spur ideas for how you can help create a security-first mindset in your own team or organization.
We’re pleased to announce an enhanced version of the AWS Secrets Manager transform: AWS::SecretsManager-2024-09-16. This update is designed to simplify infrastructure management by reducing the need for manual security updates, bug fixes, and runtime upgrades.
AWS Secrets Manager helps you manage, retrieve, and rotate database credentials, API keys, and other secrets throughout their lifecycles. Some AWS services offer managed rotation of secrets, but for other secrets, you perform rotation by using an AWS Lambda function that updates your secret and the database or service.
The AWS::SecretsManager transforms are used in conjunction with the AWS::SecretsManager::RotationScheduleresource type and HostedRotationLambdaproperty to automatically extend your CloudFormation template to include a nested stack that creates the appropriate rotation Lambda function for your database or service. The transforms provide a convenient way to deploy an AWS vended rotation Lambda function into your own account as part of your CloudFormation templates, without having to rely on creating rotation Lambda functions through the AWS Serverless Application Repository or the AWS Management Console.
In this post, we’ll explore the new features of the transform, compare them to the previous version, and guide you through updating an existing Lambda function that was created using the old transform version to use the new transform version.
New features in AWS::SecretsManager-2024-09-16
The new transform version introduces several enhancements over the previous version (AWS::SecretsManager-2020-07-23):
Automatic Lambda upgrades: Your rotation Lambda functions’ runtime configuration and internal dependencies now update automatically when you update your CloudFormation stacks. This helps you verify that you’re using the most secure and stable versions of Secrets Manager vended rotation Lambda function code and runtimes. Currently, AWS Lambda supports Python runtimes 3.9 and above. With Python 3.8 being deprecated, this feature allows for a seamless transition to newer supported runtimes. For more information on runtime deprecations, see the AWS Lambda runtimes documentation and the Python version guide.
Additional resource attributes: The new transform now supports additional resource attributes for the AWS::SecretsManager::RotationSchedule resource type when used with the HostedRotationLambda property. The following attributes are applied to the nested stack (of type AWS::CloudFormation::Stack) that creates the rotation Lambda function:
The following table shows which resource attributes are supported by the two versions of the Secrets Manager transform.
Attribute
AWS::SecretsManager-2020-07-23
AWS::SecretsManager-2024-09-16
DeletionPolicy
Supported
Supported
UpdateReplacePolicy
Supported
Supported
CreationPolicy
Not Supported
Supported
DependsOn
Not Supported
Supported
Metadata
Not Supported
Supported
UpdatePolicy
Not Supported
Supported
Condition
Not Supported
Supported
Important considerations
Before you use the AWS::SecretsManager-2024-09-16 transform, it’s essential to be aware of the following considerations so that you can make sure your CloudFormation stacks are properly created or updated:
Non-backward compatibility: The new transform version isn’t backward compatible with the previous version. If you downgrade from AWS::SecretsManager-2024-09-16 to AWS::SecretsManager-2020-07-23, the additional resource attributes won’t be supported, which might change the behavior of existing stacks.
Rollback behavior during upgrade: When you upgrade to the AWS::SecretsManager-2024-09-16 transform from the previous version and a stack rollback occurs for any reason, the rotation Lambda function might not revert to its previous state. This is because the older transform’s nested stack might not use the same Lambda deployment package that was used before the upgrade.
Direct Lambda changes: If you make direct changes to the Lambda function created by the new transform outside of a CloudFormation stack update, those modifications might be overwritten during subsequent CloudFormation stack updates or rollbacks.
Lambda runtime management: When you use the new transform version, the rotation Lambda function’s runtime aligns with the compiled binaries that are vended in Secrets Manager rotation Lambda templates, without you needing to specify a Runtime value in the HostedRotationLambda property. If you specify a Runtime value, make sure it’s the same version that is supported by Secrets Manager vended rotation Lambda templates. Otherwise, the Lambda runtime will be incompatible with the binaries that are published in the rotation Lambda function. For more information on the supported runtime, see the rotation function templates documentation.
End of support plans: AWS Secrets Manager will end support for the previous transform version (AWS::SecretsManager-2020-07-23) in the future. We recommend that you migrate your stacks to the new transform to benefit from improvements and security enhancements going forward.
How to upgrade
To upgrade to the new transform version, follow these steps:
Review your existing CloudFormation stacks that use the AWS::SecretsManager-2020-07-23 transform.
Update your CloudFormation stack templates to use AWS::SecretsManager-2024-09-16 in the Transform key at the top of your template: Transform: AWS::SecretsManager-2024-09-16
If you have previously defined a Runtime value in the HostedRotationLambda property, remove it from your template so that your rotation Lambda function’s runtime is updated properly in future stack updates.
Incorporate the new resource attributes as needed. We recommend that you minimize all other template changes while upgrading to reduce the likelihood of rollbacks.
Deploy the changes by updating your CloudFormation stack with the revised template.
By following these steps, your Secrets Manager vended rotation Lambda functions will benefit from the latest improvements and security enhancements. Remember to test the changes in a non-production environment before you apply them to your production stacks. If you encounter any issues during the upgrade process, refer to our documentation or contact AWS Support for assistance.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.