Tag Archives: serverless

A scalable, elastic database and search solution for 1B+ vectors built on LanceDB and Amazon S3

Post Syndicated from Audra Devoto original https://aws.amazon.com/blogs/architecture/a-scalable-elastic-database-and-search-solution-for-1b-vectors-built-on-lancedb-and-amazon-s3/

This post was co-authored with Owen Janson, Audra Devoto, and Christopher Brown of Metagenomi.

From CRISPR gene editing to industrial biocatalysis, enzymes power some of the most transformative technologies in healthcare, energy, and manufacturing. But discovering novel enzymes that can transform an industry — such as Cas9 for genome engineering — requires sifting through the billions of diverse enzymes encoded by organisms spanning the tree of life. Advances in DNA sequencing and metagenomics have enabled the growth of vast public and proprietary databases containing known protein sequences, but scanning through these collections to identify high value candidates is fundamentally a big data problem as well as a biological one.

At Metagenomi, we’re developing potentially curative therapeutics by using our extensive metagenomics database (MGXdb) to build a toolbox of novel gene editing systems. In this post, we highlight how Metagenomi is tackling the challenge of enzyme discovery at the billion protein scale by using the scalable infrastructure of Amazon Web Services (AWS) to build a high-performance protein database and search solution based on embeddings. By embedding every protein in our large proprietary database into a vector space, making the data accessible using LanceDB built on Amazon Simple Storage Service (Amazon S3), and accessed with AWS Lambda, we were able to transform enzyme discovery into a nearest neighbor search problem and rapidly access previously unexplored discovery space.

Solution overview

At the core of our solution is LanceDB. LanceDB is an open source vector database that enables rapid approximate nearest neighbor (ANN) searches on indexed vectors. LanceDB is particularly well suited for a serverless stack because it’s entirely file-based and is also compatible with Amazon S3 storage. As a result, we can store our database of embedded protein sequences on relatively low-cost Amazon S3, rather than a persistent disk storage such as Amazon Elastic Block Store (Amazon EBS). Instead of constantly running servers, all that is needed to rapidly query the database on-demand is a Lambda function that uses LanceDB to find nearest neighbors directly from the data on S3.

To overcome the challenge of ingesting and querying billions of vector embeddings representing Metagenomi’s large protein database, we devised a method for splitting the database into equal sized parts (folders) stored for low cost on Amazon S3 that can be indexed in parallel and searched with a map-reduce approach using Lambda. The following diagram illustrates this architecture.
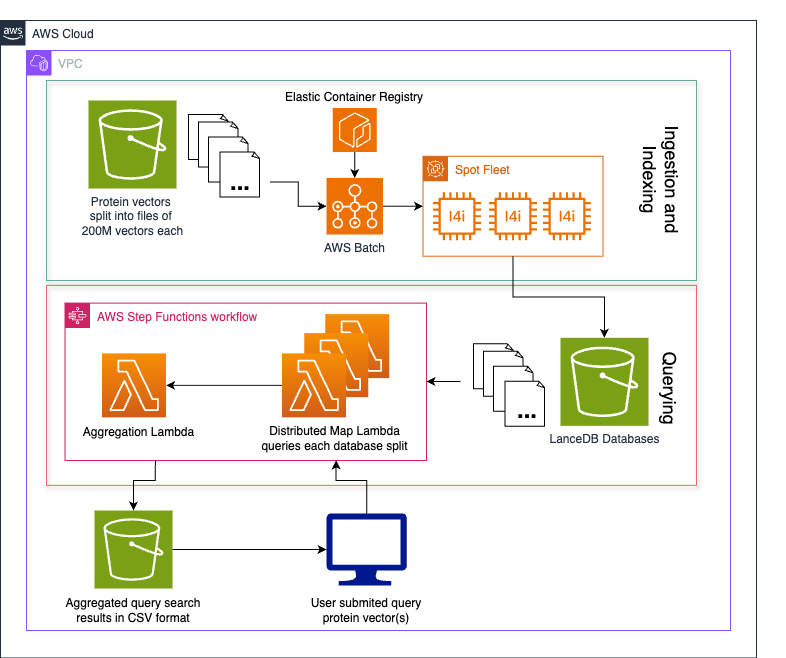
AWS architecture showing protein vector processing workflow with ECR, Lambda, and LanceDB

The process follows four steps:

  1. Data vectorization
  2. Data bucketing
  3. Indexing and ingesting data
  4. Querying the database

Data vectorization

To make use of LanceDB’s fast ANN search capabilities, the data must be in vector form. Our metagenomics database consists of billions of proteins, each a string of amino acids. To convert each protein into a vector that captures biologically meaningful information, we run them through a protein language model (pLM), capturing the model’s hidden layers as a vector representation of that protein. Many pLMs can be used to generate protein embeddings, depending on the desired biological information and computational requirements. Here, we use the AMPLIFY_350M model, a transformer encoder model that is fast enough to scale to our entire protein database. We perform a mean-pool of the final hidden layer of the model to produce a 960-dimension vector for each protein. These vectors and their respective unique protein IDs are then stored in HDF5 files.

Data bucketing

To turn our protein vectors into a searchable database, we use LanceDB to build an index suitable for quickly finding ANNs to a query. However, indexing can take a long time and is difficult to distribute across nodes. To speed up indexing, we first divide our data into roughly evenly sized buckets. We then assign each of our embedding HDF5 files to buckets of size roughly equal to 200 million total vectors using a best-fit bin packing algorithm. The exact size packing method used to bucket data depends on the number and dimension of the vectors, as well as their format. Each bucket is ingested into a separate table that will separately reside in a single LanceDB database object store on Amazon S3.
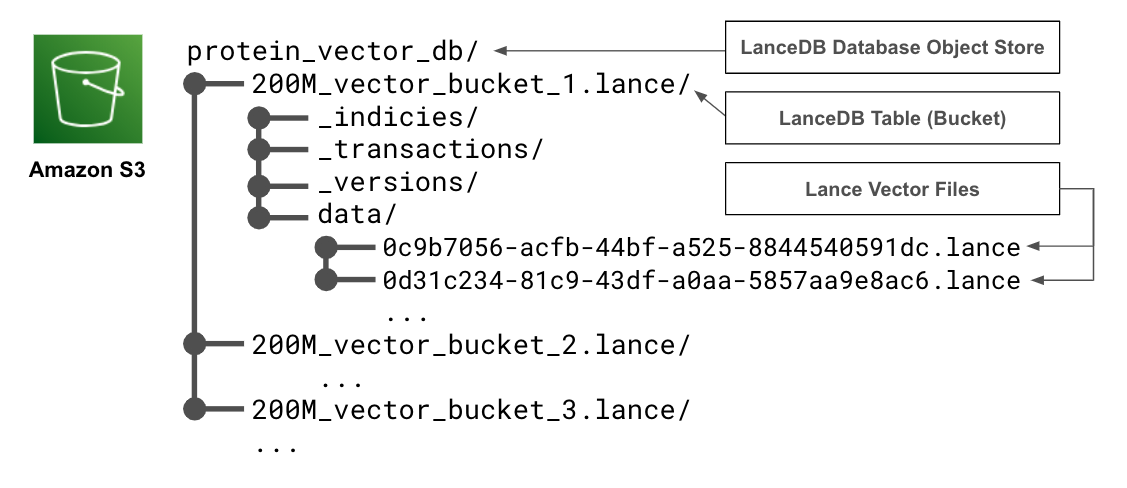
S3 bucket structure showing LanceDB database organization with vector buckets

By bucketing our data, we can produce several smaller databases that can be indexed on separate nodes in a much shorter amount of time. We can also add more data to our database incrementally as a new bucket, instead of reindexing all the existing data.

Ingesting and indexing bucketed data

After the vectorized data has been assigned to a bucket, it’s time to turn it into a LanceDB table and index it to enable fast ANN querying. The details on how to convert your specific data into a LanceDB table can be found in the LanceDB documentation. For each of our buckets of approximately 200 million vectors, we create a LanceDB table with an IVF-PQ index on the cosine distance. For indexing, we use several partitions equal to the square root of the number of inserted rows, and several sub vectors equal to the number of dimensions of our vectors divided by 16.

To make things smoother to query, we name each table after the bucket from which it was created and upload them to a single S3 directory such that their file structure indicates a single LanceDB database with multiple tables.

The following code snippet provides an example of how you might ingest vectors from an HDF5 file containing id and embedding columns into a LanceDB database and index for fast ANN searches based on cosine distance. The only requirements for running this snippet are python >= 3.9, as well as the lancedb, pyarrow, and h5py packages. It should be noted that this snippet was tested and developed using lancedb version 0.21.1 using the asynchronous LanceDB API.

from typing import List, Iterable
from itertools import islice
from math import sqrt
import pyarrow as pa
import datetime
import asyncio
import lancedb
import h5py

def batched(iterable: Iterable, n: int) -> Iterable[List]:
    """Yield batches of n items from iterable."""
    while batch := list(islice(iterable, n)):
        yield batch

async def vectors_to_db(
    vectors: str,
    db: str,
    table_name: str,
    vector_dim: int,
    ingestion_batch_size: int,
) -> int:
    """Ingest and index vectors from an HDF5 file into a LanceDB table.
    Args:
        vectors (str): An HDF5 file containing protein IDs and their
            960-dimension vector representations.
        db (str): Path to the LanceDB database.
        table_name (str): Name of the table to create.
        vector_dim (int): Dimension of the vectors.
    """
    # create db and table
    custom_schema = pa.schema(
        [
            pa.field("embedding", pa.list_(pa.float32(), vector_dim)),
            pa.field("id", pa.string()),
        ]
    )

    # count the total number of rows as they are added to the table
    total_rows = 0

    # open a connection to the new database and create a table
    with await lancedb.connect_async(db) as db_connection:
        with await db_connection.create_table(
            table_name, schema=custom_schema
        ) as table_connection:
            # open vectors file
            with h5py.File(vectors, "r") as vectors_handle:
                # create a generator over the rows
                rows = (
                    {"embedding": e, "id": i}
                    for e, i in zip(
                        vectors_handle["embedding"],
                        vectors_handle["id"],
                    )
                )

                # insert rows in batches to avoid memory issues
                for batch in batched(rows, ingestion_batch_size):
                    total_rows += len(batch)
                    await table_connection.add(batch)

            # optimize the table and remove old data
            await table_connection.optimize(
                cleanup_older_than=datetime.timedelta(days=0)
            )

            # configure the index for the table
            index_config = lancedb.index.IvfPq(
                distance_type="cosine",
                num_partitions=int(sqrt(total_rows)),
                num_sub_vectors=int(
                    vector_dim / 16
                ),
            )

            # index the table
            await table_connection.create_index(
                "embedding", config=index_config
            )

# ingest and index your data
asyncio.run(
    vectors_to_db(
        vectors="./my_vectors.h5",
        db="./test_db",
        table_name="bucket1",
        vector_dim=960,
        ingestion_batch_size=50000
    )
)

The task of vectorizing, ingesting, indexing each bucket could be parallelized over multiple AWS Batch jobs or run on a single Amazon Elastic Compute Cloud (Amazon EC2) instance.

Querying the database

After the data has been bucketed and ingested into a LanceDB database on Amazon S3, we need a way to query it. Because LanceDB can be queried directly from Amazon S3 using the LanceDB Python API, we can use Lambda functions to take a user-provided query vector and search for ANNs, then return the data to the user. However, because our data has been bucketed across several tables in the database, we need to search for nearest neighbors in each bucket and aggregate the results before passing them back to the user.

We implement the query workflow as an AWS Step Functions state machine that manages a query process for each bucket as Lambda processes, as well as a single Lambda process at the end that aggregates the data and writes the resulting ANNs to a .csv file on Amazon S3. However, this could also be implemented as a series of AWS Batch processes or even run locally. The following snippet shows how a process assigned to one bucket could run an ANN query against one of the database’s buckets, requiring only pandas and lancedb to run on python >= 3.9. As detailed before in the ingestion section, we use the asynchronous LanceDB API and lancedb package version 0.21.1.

from typing import List, Iterable
import asyncio
import lancedb
import pandas
import random

async def run_query_async(
    lancedb_s3_uri: str,
    table_name: str,
    q_vec: List[float],
    k: int,
    vec_col: str,
    n_probes: int,
    refine_factor: int,
) -> pandas.DataFrame:
    """Run a query on a LanceDB table.
    Args:
        lancedb_s3_uri (str): S3 URI of the LanceDB database.
        table_name (str): Name of the table to query.
        q_vec (List[float]): Query vector.
        k (int): Number of nearest neighbors to return.
        vec_col (str): Column name of the vector column.
        n_probes (int): Number of probes to use for the query.
        refine_factor (int): Refine factor for the query.
    Returns:
        pandas.DataFrame: DataFrame containing the approximate nearest
        neighbors to the query vector.
    """
    # open a connection to the database and table
    with await lancedb.connect_async(
        lancedb_s3_uri, storage_options={"timeout": "120s"}
    ) as db_connection:
        with await db_connection.open_table(table_name) as table_connection:
            # query the approximate nearest neighbors to the query vector
            df = (
                await table_connection.query()
                .nearest_to(q_vec)
                .column(vec_col)
                .nprobes(n_probes)
                .refine_factor(refine_factor)
                .limit(k)
                .distance_type("cosine")
                .to_pandas()
            )

    return df

# query the example bucket we produced in the last section
bucket1_df = asyncio.run(
    snippets.run_query_async(
        lancedb_s3_uri="s3://mg-analysis/owen/20250415_lancedb_snippet_testing/test_db/",
        table_name="bucket1",
        q_vec=[random.random() for _ in range(960)],
        k=3,
        vec_col="embedding",
        n_probes=1,
        refine_factor=1,
    )
)

The preceding query will return a panda DataFrame of the following structure:

embedding id _distance
[-5.124435, 4.242000, …] id_1 0.000000
[-5.783999, 4.340500, …] id_2 0.001000
[-6.932943, 3.394850, …] id_3 0.04020

Where the embedding column contains the vector representations of the nearest neighbors, the id column their IDs, and the _distance column their cosine distances to the queried vector.

After each bucket has been independently queried across nodes and each has returned a nearest neighbors DataFrame, the results must be merged and subset to return the user. The following snippet shows how you might do this.

def aggregate_nearest_neighbors(
    dfs: List[pandas.DataFrame], k: int
):
    """Aggregate the nearest neighbors for each query vector.
    Args:
        dfs (List[pandas.DataFrame]): A list of DataFrames containing the
            nearest neighbors queried from each bucket.
        k (int): The number of nearest neighbors to aggregate.
    Returns:
        pd.DataFrame: A DataFrame with the aggregated nearest neighbors.
    """
    # concatenate the DataFrames and get the top k nearest neighbors
    return (
        pandas.concat(dfs, ignore_index=True)
        .sort_values(by=["_distance"], ascending=True)
        .reset_index(drop=True)
        .head(k)
    )

# add the dataframes from querying each bucket to a list
dfs = [bucket1_df, bucket2_df, bucket3_df, bucket4_df, bucket_5]

# aggregate the nearest neighbors across all buckets
nearest_neighbors_all_buckets_df = aggregate_nearest_neighbors(dfs, 5)

Optimizing for large batches of queries

Though querying a LanceDB database directly from its S3 object store on Lambda works well for querying the ANNs of one or a few query vectors, some use cases might require querying thousands or even millions of vectors.

One solution we’ve found that scales well to large batches of queries is to modify the preceding query implementation such that it first downloads one of the database buckets to local storage, then queries it locally using the LanceDB API. Because database buckets can have a large storage footprint, this implementation is better suited for AWS Batch jobs than Lambda, and we recommend using optimized instance storage (for example, i4i instances) rather than EBS volumes. After all query Batch jobs finish, a final job can aggregate their results before returning to the user. Orchestration of parallel query jobs and the aggregation job can be done with Nextflow. Though this implementation will have significantly more overhead and latency from downloading the buckets to disk, it can handle larger batches of queries more efficiently and still requires no continuously running server-based database.

Benchmarking results

Indexing strategies and database split sizes depend on your personal need for performance. Consider the following general optimization guidance when customizing to your use case.

An example database created by Metagenomi consisted of 3.5 billion vector embeddings produced by AMPLIFY, of dimension 960. Ingesting and indexing these 3.5B vector embeddings in split sizes of 200M vectors on i4i.8xlarge instances took 108 total compute hours. Because this solution is serverless and can be queried directly from its S3 object store, the only fixed cost of this database is its storage footprint on Amazon S3 (for an indexed database of 3.5B vectors, this is approximately 12.9 TB). Lambda queries can be an exceptionally low-cost querying solution, with many queries costing fractions of a cent.

In general, larger database splits will be more cost effective to query but will result in longer runtimes and longer indexing times. We recommend scaling up database split sizes to the maximum size that results in an acceptable query return time for a single split while also considering limits of parallelization such as maximum concurrent Lambda functions running. Metagenomi identified database splits of 200M vectors each to yield an optimal trade-off in cost and runtime for both small and large queries. We recommend ingesting and indexing on storage-optimized instances, such as those in the i4i family, for optimal performance and cost savings. If querying is to be done on an instance using a disk-based database (as opposed to Lambda and Amazon S3), we also recommend using storage-optimized instances for queries. We found the Lambda implementation could quickly handle single queries requesting up to 50,000 ANNs, or multi queries of up to 100 sequences with fewer than 5 ANNs. Runtime increases linearly with the number of ANNs requested, as shown in the following graph.
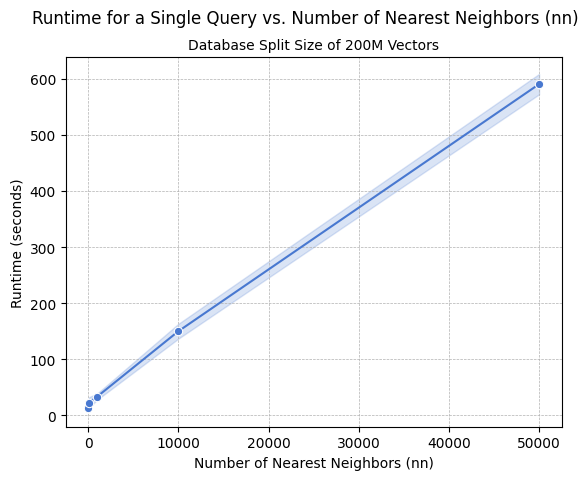
Line graph showing query runtime increasing with number of nearest neighbors

Conclusion

In this post, we showed how Metagenomi was able to store and query billions of protein embeddings at low cost using LanceDB implemented with Amazon S3 and AWS Lambda. This work expands on Metagenomi’s patient-driven mission to create curative genetic medicines by accelerating our discovery and engineering platform. Having quick access to the ANN embedding space of a query protein in seconds has enabled the integration of rapid search methods in our extensive analysis pipelines, accelerated the discovery of several diverse and novel enzyme families, and enabled protein engineering efforts by providing scientists with methods to generate and search embeddings on the fly. As Metagenomi continues to rapidly scale protein and DNA databases, horizontal scaling enabled by database splits that can be indexed and searched in parallel facilitates an embedding database solution that scales to future needs.

The solution outlined in this post focuses on vectors produced by a protein large language model (LLM) but can be applied to other vectorized datasets. To learn more about LanceDB integrated with Amazon S3, refer to the LanceDB documentation.

References

  1. Fournier, Quentin, et al. “Protein language models: is scaling necessary?.” bioRxiv (2024): 2024-09.

About the authors

A Lookback at Workers Launchpad and a Warm Welcome to Cohort #6

Post Syndicated from Christopher Rotas original https://blog.cloudflare.com/workers-launchpad-006/

Imagine you have an idea for an AI application that you’re really excited about — but the cost of GPU time and complex infrastructure stops you in your tracks before you even write a line of code. This is the problem founders everywhere face: balancing high infrastructure costs with the need to innovate and scale quickly.
Our startup programs remove those barriers, so founders can focus on what matters the most: building products, finding customers, and growing a business. Cloudflare for Startups launched in 2018 to provide enterprise-level application security and performance services to growing startups. As we built out our Developer Platform, we pivoted last year to offer founders up to $250,000 in cloud credits to build on our Developer Platform for up to one year.

During Birthday Week 2022, we announced our Cloudflare Workers Launchpad Program with an initial $1.25 billion in potential funding for startups building on Cloudflare Workers, made possible through partnerships with 26 leading venture capital (VC) firms. Within months, we expanded VC-backed funding to $2 billion.

Since 2022, we’ve welcomed 145 startups from 23 countries. These startups are solving problems across verticals such as AI and machine learning, developer tools, 3D design, cloud infrastructure, data tools, ad tech, media, logistics, finance, and other industries. We’re especially proud of the female founder representation in recent cohorts — with nearly a third of companies in Cohort #5 run by a female founder. 

Participants engaged in bootcamp sessions with Cloudflare leadership and product teams, covering key topics like product pricing and scaling sales. Startups received hands-on design support from our Solutions Architecture team, empowering these builders to build and scale their full-stack applications on the Cloudflare network. We facilitate countless introductions across the VC network, and are happy to see funding and M&A activity as these startups scale. Cloudflare also identified direct opportunities and acquired Nefeli Networks (Cohort #2) and Outerbase (Cohort #4).

Check out what Launchpad alumni have to say about their experience in the program:

Langbase (Cohort #3)
Ship hyper-personalized AI apps to any LLM, any data, any developer in seconds


“For Langbase, the best part about Workers Launchpad was the incredible support from Cloudflare’s internal teams. It wasn’t just about access to infrastructure; it was the hands-on migration help, rapid feedback loops, and genuine partnership from engineers, product folks, and the broader Cloudflare community. That human support empowered us to iterate faster, solve hard problems, and truly feel like we were building something impactful together. 

Langbase has quickly become one of the most powerful serverless AI clouds for building and deploying AI agents. We process 700 TB of agent memory and 1.2 billion AI agent runs a month. Langbase is an agent lab, and we’ve also launched a coding agent called Command.new, an “agent of agents” that can take your prompts and turn them into production-ready agents by provisioning infrastructure and writing the agent’s code in TypeScript.

My advice for anyone joining future Workers Launchpad cohorts is to use every resource offered. Engage deeply with the Cloudflare teams, ask for feedback early and often, and be open to sharing your challenges and wins, especially in the Discord community, which is super helpful. Cloudflare listens closely to participant feedback and genuinely wants to help startups succeed. Treat it as a two-way conversation and a collaborative growth opportunity. This mindset is what unlocks the real power of the program.”

-Ahmad Awais, Founder & CEO of Langbase

Sherpo.io (Cohort #4)
AI-first no-code platform to build and sell digital content


“Since joining Cohort #4, we’ve exited closed beta and expanded our product suite for content creators. Today, more than 3,000 creators worldwide power their digital product stores with Sherpo, while we continue building and scaling.

We learned as much from fellow startups as from Cloudflare during office hours and sessions, and we got to meet incredible people along the way, including Cloudflare’s CSO, Stephanie Cohen.

For anyone joining, attend every session, listen closely, and ask questions—they’re incredibly valuable. Building on Workers has given us a real advantage, and the team’s pace of innovation only compounds it.”

-Giacomo Di Pinto, Co-Founder & CEO of Sherpo.io

Tightknit AI (Cohort #4)
Embedded community engagement platform built for SaaS


“Beyond the cloud credits that Launchpad provided us to play with every Cloudflare product, the most important aspect of the program we found was our ability to access (and even contribute) to the product roadmap. We were able to connect with product managers and solutions architects that have helped us take our work to the next level.

We’ve recently passed half a million users on the platform and have started to close not just the top Saas businesses in the world, but the top AI companies in the world, including Clay, Gamma, Lindy, beehiiv, Amplitude, Mixpanel, and so many more. The best part is that 100% of application logic is still powered by Cloudflare!

The biggest piece of advice for anyone starting the cohort is attend office hours as much as you can. I can’t tell you how many times we were able to unblock ourselves or even provide real product feedback/bug reports. It was amazing to meet the rest of the cohort and solve problems together that ordinary Cloudflare developers just do not face. So my advice is don’t miss the office hours. They were by far the most valuable part of our experience.”

-Zach Hawtof, Co-Founder & CEO of Tightknit.ai

Render Better (Cohort #4)
Increase e-commerce revenue by automatically optimizing your site speed


“My favorite part of the Launchpad was the community and the leaders who brought us together. The startup and product teams provided expert advice on both business and technical questions through meetings, 1-on-1s, and Discord. Many of them were former founders, so they understood what we were going through and helped us get what we needed. They were crucial in helping us get unstuck, whether we were using obscure Cloudflare features or needed connections to the right people.

I met a lot of great founders who are on the same journey and face the same struggles. Watching them grow was motivating and gave us a morale boost to keep up the fast pace a startup needs.

Since Launchpad, Render Better has scaled to 60 automated site speed optimizations, helping e-commerce sites convert 20% higher powered by Cloudflare Workers. Our growth accelerated after the program, and we’re now optimizing traffic for some of the biggest e-commerce brands like PSD, Polywood, and Self-Portrait. Render Better now processes 5 billion requests each month, made possible by Cloudflare’s global edge network and Workers platform.

Launchpad is truly just that: Cloudflare gives you the resources and attention to help you grow from an idea into something big. Build fast and take as much advantage of the fuel they give you to fly your startup rocket!”

-James Koshigoe, Founder & CEO of Render Better

Launchpad is growing into more than just a program. It is a community of builders and innovators showing what is possible with Cloudflare’s network behind them. With that foundation, we are excited to introduce the next group of entrepreneurs taking the stage in Cohort #6.

Introducing Cohort #6

Before introducing Cohort #6, we want to give one last shout out to Cohort #5. As Launchpad alumni, we cannot wait to see what you achieve. If you didn’t get a chance to check out Cohort #5’s demo day, watch  the recording here.

With that, help us give a warm welcome to the participants of Workers Launchpad Cohort #6:


We’re excited to see what Cohort #6 accomplishes. Follow @CloudflareDev on X and join our Developer Discord to stay updated on their progress. If you’re a startup interested in joining Workers Launchpad, applications for Cohort #7 are now open.

Company

About

Allegory

AI-Powered platform connecting impact to funding

Apgio

Mobile app localization platform with smart AI translations and workflow tooling

Atlas

Building the operating system for restaurants

Bloctave

Configurable rights management platform with instantaneous royalty distribution

Byte

AI code auditor that translates codebases into natural language

Calljmp

Agentic AI backend for apps

Centian

MCP-powered AI Agent middleware for successful and compliant operations

Divinci AI

Release management and quality assurance for custom LLMs

DXOS

An extensible open-core super-app designed to be your team’s brain

Fidsy

AI-native, code-free orchestration platform providing automated data privacy for all AI & Data workflows

Fluentos

Create popups your customers won’t hate

Framebird

Media sharing solution for creatives featuring modern galleries and client review tools

GoPersonal

AI to build, personalize, and manage your ecommerce business

Horizon

Short-form & agentic experiences for apps and websites

Kenobi

Personalizing the Internet with custom web experiences

MonetizationOS

Intelligent decisioning at the edge, for monetising the human and machine web

Natively.dev

Build your dream mobile app using AI, enabling users to take directly to App Stores

Outhire

AI agent automating phone screens without bias

Outsession

Privacy-first AI tools that preserve the therapeutic relationship

Phleid

Direct-to-wallet mobile passes and notifications platform

PlaySafe (By Doge Labs)

Makes voice-chat communities safer by detecting and blocking harassment in real time

Ploton

Help small business businesses grow by building workflows through natural conversation, not complex tools

Project Karna

Multimodal, continuous identity for the post-GenAI enterprise

Schematic

Simplify monetization for GTM teams, allowing them to control pricing, packaging, and entitlements without code changes

SonicLinker

Turn AI-agent visits into revenue

SuiteOp

All-in-one platform to streamline hospitality operations and guest services

SuprSend

Multi-channel notification engine for product and platform teams

Yara AI

Ethical, memory-rich AI for mental health at scale

Zephyr Cloud

Fastest way to go from idea to production

Zero Email

AI native email client that manages your inbox so you don’t have to

Introducing free access to Cloudflare developer features for students

Post Syndicated from Veronica Marin original https://blog.cloudflare.com/workers-for-students/

I can recall countless late nights as a student spent building out ideas that felt like breakthroughs. My own thesis had significant costs associated with the tools and computational resources I needed. The reality for students is that turning ideas into working applications often requires production-grade tools, and having to pay for them can stop a great project before it even starts. We don’t think that cost should stand in the way of building out your ideas.

Cloudflare’s Developer Platform already makes it easy for anyone to go from idea to launch. It gives you all the tools you need in one place to work on that class project, build out your portfolio, and create full-stack applications. We want students to be able to use these tools without worrying about the cost, so starting today, students at least 18 years old in the United States with a verified .edu email can receive 12 months of free access to Cloudflare’s developer features. This is the first step for Cloudflare for Students, and we plan to continue expanding our support for the next generation of builders.


What’s included

12 months of our paid developer features plan at no upfront cost

Eligible student accounts will receive increased usage allotments for our developer features compared to our free plan. That includes Workers, Pages Functions, KV, Containers, Vectorize, Hyperdrive, Durable Objects, Workers Logpush, and Queues. With these, you can build everything from APIs and full-stack apps to data pipelines and websites.

After 12 months, you can easily renew your subscription by upgrading to our Workers Paid plan. If you choose not to, your account will automatically revert to the free plan, and you won’t be charged.

Here’s a look at the increased usage allotments students can receive today. Above those free allotments, our standard usage rates will apply.

Free Plan

Student Accounts (Paid developer features)

Workers

100,000 requests/day

10 million requests/month

+ $.30 per additional million requests

Workers KV

100,000 read operations/day

1,000 write, delete, list operations per day

10 million read operations/month

1 million write, delete, and list operations per month

Hyperdrive

100,000 database queries/day

Unlimited database queries / day

Durable Objects

100,000 requests/day

1 million requests / day

+ $0.15 / per additional million requests

Workers Logs

200,000 log events / day

3 Days of retention

20 million log events / month 

7 Days of retention

+$0.60 per additional million events

Workers Logpush

Not Included

10 million log events / month

+$0.05 per additional million log events

Queues

Not Included

1 million operations/month included 

+$0.40 per additional million operations

Access to a dedicated student developer community

You’ll also have access to a dedicated Discord channel just for students. We want to see what you’re building! This is a place to connect with peers, get support, and share ideas in a community of student developers.

What others have built with Cloudflare’s Developer Platform

Curious about what’s possible with Cloudflare’s developer features? Here are some projects from our community:

by Daniel Foldi


Adventure is a text-based adventure game running on Cloudflare Workers that uses Workers AI to generate the stories with the @cf/google/gemma-3-12b-it model. 

The project’s developer chose Workers AI with the OpenNext adapter because it made deployment simple and handled scaling automatically. It uses the Workers Paid plan mainly to enable Workers Logpush and get access to detailed logs for better monitoring and analysis.

When a new game starts, the server gives the AI a custom prompt to set the scene and explain how the adventure should work. From there, each time the player makes a choice, their story history is sent back to the server, which asks the AI to continue the narrative, allowing the story to evolve dynamically based on the player’s choices.

The code below shows how this logic is implemented:

"use server";
import { getCloudflareContext } from "@opennextjs/cloudflare";

async function prime(env: CloudflareEnv) {
  const id = Math.floor(Math.random() * 1000000);//unique ID for each game run
  const messages = [
    {
      role: "user",
      content:
        `The user is playing a text-based adventure game. Each game is different, this is game ${id}. Your first job is to create a short background story in 3-4 sentences. Scenarios may include interesting locations such as jungles, deserts, caves.
        After the first message, each of your messages will be responses to the user interaction. State three short options (A, B, C). The user responses will be the chosen action. Your responses should end by asking the user about their choice.
        Your message will be shown to the user directly, so avoid "Certainly", "Great", "Let's get started", and other filler content, and avoid bringing up technical details such as "this is game #id".
        The games should have a win condition that is actually feasible given the story, and if the player loses, the message should end with "Try again.".
        `,
    },
  ];
  //Call Workers AI to generate the first response (story intro)
  const { response } = await env.AI.run("@cf/google/gemma-3-12b-it", { messages });

  return [
    ...messages,
    { role: "assistant", content: response }
  ];
}

/**
 * Main server action for the adventure game.
 * If no input yet, it primes the game with the opening story
 * If there is input, it continues the story based on the full history
 * Uses getCloudflareContext from @opennextjs/cloudflare to access env.
 */
export async function adventureAction(input: any[]) {
  let { env } = await getCloudflareContext({ async: true });

  return input.length === 0
  ? await prime(env)
  : [...input,
      { role: "assistant", content: (await env.AI.run("@cf/google/gemma-3-12b-it", { messages: input })).response }
  ];
}

by Matt Cowley


DNS over Discord is a bot that lets you run DNS lookups right inside Discord. Instead of switching to a terminal or online tool, you can use simple slash commands to check records like A, AAAA, MX, TXT, and more.

The developer behind the project chose Cloudflare Workers because it’s a great platform for running small JavaScript apps that handle requests, which made it a good fit for Discord’s slash commands. Since every command translates into a request and the bot sees a lot of traffic, the free tier wasn’t enough, so it now runs on Workers Paid to keep up reliably without hitting request limits.

In this project, the Worker checks if the request is a Discord interaction, and if so, it sends it to the right command (e.g., /dig, /multi-dig, etc.), using a handler that calls out to a custom framework for Discord slash commands. If it’s not from Discord, it can also serve routes like the privacy page or terms of service.

Here’s what that looks like in code:

export default {
  // Process all requests to the Worker
  fetch: async (request, env, ctx) => {
    try {
      // Include the env in the context we pass to the handler
      ctx.env = env;

      // Check if it's a Discord interaction (or a health check)
      const resp = await handler(request, ctx);
      if (resp) return resp;

      // Otherwise, process the request
      const url = new URL(request.url);

      if (request.method === 'GET' && url.pathname === '/privacy')
        return new textResponse(Privacy);

      if (request.method === 'GET' && url.pathname === '/terms')
        return new textResponse(Terms);

      // Fallback if nothing matches
      return new textResponse(null, { status: 404 });
    } catch (err) {
      // Log any errors
      captureException(err);

      // Re-throw the error
      throw err;
    }
  },
};

by James Ross


placeholders.dev is a service that generates placeholder images, making it easy for developers to prototype and scaffold websites without dealing with hosting or asset management. Users can generate placeholders instantly with a simple URL, such as: https://images.placeholders.dev/350x150

Since placeholders are typically used in early development, speed and consistency matter, and images need to load instantly so the workflow isn’t interrupted. Running on Cloudflare Workers makes the service fast and consistent no matter where developers are.

This project uses the Workers Paid plan because it regularly exceeds the free-tier limits on requests and compute time. The Worker below shows the core of how the service works. When a request comes in, it looks at the URL path (like /300x150) to determine the size of the placeholder, applies some defaults for style, and then returns an SVG image on the fly.

export default {
  async fetch(request: Request, env: Env, ctx: ExecutionContext) {
    try {
      const url = new URL(request.url);
      const cache = caches.default;

      // Handle requests for the placeholder API
      if (url.host === 'images.placeholders.dev' || url.pathname.startsWith('/api')) {
        // Try edge cache first
        const cached = await cache.match(url, { ignoreMethod: true });
        if (cached) return cached;

        // Default placeholder options
        const imageOptions: Options = {
   dataUri: false, // always return an unencoded SVG source
          width: 300,
          height: 150,
          fontFamily: 'sans-serif',
          fontWeight: 'bold',
          bgColor: '#ddd',
          textColor: 'rgba(0,0,0,0.5)',
        };

        // Parse sizes from path (e.g. /350 or /350x150)
        const sizeParts = url.pathname.replace('/api', '').replace('/', '').split('x');
        if (sizeParts[0]) {
          const width = sanitizeNumber(parseInt(sizeParts[0], 10));
          const height = sizeParts[1] ? sanitizeNumber(parseInt(sizeParts[1], 10)) : width;
          imageOptions.width = width;
          imageOptions.height = height;
        }

        // Generate SVG placeholder
        const response = new Response(simpleSvgPlaceholder(imageOptions), {
          headers: { 'content-type': 'image/svg+xml; charset=utf-8' },
        });

        // Cache result
        response.headers.set('Cache-Control', 'public, max-age=' + cacheTtl);
        ctx.waitUntil(cache.put(url, response.clone()));

        return response;
      }

      return new Response('Not Found', { status: 404 });
    } catch (err) {
      console.error(err);
      return new Response('Internal Error', { status: 500 });
    }
  },
};

Check out Built With Workers to see what other developers are building with our developer platform.


How do I get started?

This offering is available to United States students at least 18 years old with a verified .edu billing email address.

Based on when your account was created, you can redeem this offer either by signing up for a free Cloudflare account with your .edu email or by filling out a form to request access for your existing .edu account. Just make sure your verified .edu email address is your billing email address.

New .edu accounts

Existing .edu accounts

Creation Date 

Created on/after September 22, 2025

Created prior to September 22, 2025

How to Redeem

Sign up for a free Cloudflare account, add your credit card and ensure your verified .edu email address is added to your billing details.

Ensure your verified .edu email address is added to your billing details.

Fill out our form and a member of our team will help you get access

Note: in order to receive the credit, your verified .edu email address needs to be your billing email address 

Expanding Cloudflare for Students coverage

While our first offering is primarily for institutions in the US, we’re working on expanding support for our students in other countries and plan to add additional higher education domain names after launch. If you’re at an educational institution outside of the United States, please reach out to us and apply for your educational/academic domain to be added. We’ll let you know as soon as it becomes available in your region. Check our Cloudflare for Students page for updates and keep an eye out for emails if you have an account with a newly supported domain.

Whether you’re gearing up for your first hackathon, launching a side project, or looking to build the next big thing, you can get started today with free access and join a global developer community already building on Cloudflare.

Get started by signing up or requesting access today.


Come build with us: Cloudflare’s new hubs for startups

Post Syndicated from Christopher Rotas original https://blog.cloudflare.com/new-hubs-for-startups/

Cloudflare’s offices bring together builders in some of the world’s most popular technology hubs. We have a long history of using those spaces for one-off events and meet ups over the last fifteen years, but we want to do more. Starting in 2026, we plan to open the doors of our offices routinely to startups and builders from outside of our team who need the space to collaborate, meet new people, or just type away at a keyboard in a new (and beautiful) location.

What are our offices meant to be?

Prior to 2020, we expected essentially every team member of Cloudflare to be present in one of our offices five days a week. That worked well for us and helped facilitate the launch of dozens of technologies as well as a community and culture that defined who we are.

Like every other team on the planet, the COVID pandemic forced us to revisit that approach. We used the time to think about what our offices could be, in a world where not every team member showed up every day of the week. While we decided we would be open to remote and hybrid work, we still felt like some of our best work was done in person together. The goal became building spaces that encouraged team members to be present.

Several hard hats and a few leases later, we’ve created a network of offices around the world designed to evolve with the way people work. These spaces aren’t just places to sit — they’re environments that empower people to do their best work — whether that means quiet focus, creative problem-solving, or lively collaboration. From a library tucked into a quiet zone in our waterfront Lisbon office, to the high-ceilinged collaboration areas in the heart of Austin, each office reflects our belief that great spaces support diverse working styles and help teams thrive together.

Our offices are meant to connect our teams, and we believe that by opening our doors to the wider community, we can foster even more innovation and help new companies collaborate better. Cloudflare has always been a hub for builders, and now we’re making that commitment official by welcoming startups into our physical spaces.

Why make them even more open to the community?

Our spaces have served as hosts to community events since the earliest days of Cloudflare. We have brought together just about every group from hackathons to language meet-ups to university orientation sessions. Cloudflare exists to help build a better Internet and in many cases a better digital environment starts with relationships built in a real life environment.

One of the most common pieces of feedback we have received in the last few years after hosting these events is “I really miss connecting with people like this.” And we hear that most often from small teams in the earliest stages of their journey. In the last few years as the start-ups we support with our platform increasingly begin remote-first and only open dedicated spaces in later stages of their growth.

We know that building a company can be a lonely path. We have helped over the last several years by providing a robust free plan and a comprehensive start-up program, but we think we can do more.

Cloudflare’s network supports a significant percentage of the Internet and, as you would expect, the Internet follows the sun. More people use it during the daytime than at night, meaning our data center utilization peaks in specific times of the day. We take advantage of that pattern to run services that are less latency-sensitive in regions overnight.

Our physical locations follow a similar pattern. Utilization resembles a bell curve with Tuesdays, Wednesdays, and Thursdays seeing a lot of traffic while Mondays and Fridays tend to be quieter. Like our CPUs at night, we think we can use that excess capacity to help build a better Internet by giving builders a space to congregate and helping our team connect with more of our users.

How will this work?

Beginning in January of 2026, we plan to make our office locations available to a capped number of external visitors as all-day coworking spaces on select days of each week. We will provide a registration process (more on that below) and set some ground rules. To start, we plan to expand this offering to San Francisco, Austin, London, and Lisbon.

When external visitors arrive, they’ll have access to our common spaces to bring together their teams or just get some work done by themselves. No mandatory talks or obligations. Just fantastic working spaces available to use at no cost.

How can you participate?

We will provide more details in the next few weeks, but the general structure will be based on the following steps.

  1. Enroll in the Cloudflare for Startups Program. Bonus if you are a Workers Launchpad participant or alumni.

  2. Sit tight for now. We will email participating Startup Program customers first to participate with a form requesting office access.

  3. Once the form is filled out, a member of our team will reach out after. If you want to get a head start, fill out the form here.

  4. We plan to roll this out on a cohort basis. Once approved and all requirements are met, register your visit (and that of any additional team members) at least three business days prior to the date requested.

  5. Respect our working spaces as you would your own.

What’s next?

We hope to expand to other locations in the future. Want to get to the front of the line? Sign up for our Startup program here today and we will reach out to Startup Program participants before we roll out the program.

Qwen models are now available in Amazon Bedrock

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/qwen-models-are-now-available-in-amazon-bedrock/

Today we are adding Qwen models from Alibaba in Amazon Bedrock. With this launch, Amazon Bedrock continues to expand model choice by adding access to Qwen3 open weight foundation models (FMs) in a full managed, serverless way. This release includes four models: Qwen3-Coder-480B-A35B-Instruct, Qwen3-Coder-30B-A3B-Instruct, Qwen3-235B-A22B-Instruct-2507, and Qwen3-32B (Dense). Together, these models feature both mixture-of-experts (MoE) and dense architectures, providing flexible options for different application requirements.

Amazon Bedrock provides access to industry-leading FMs through a unified API without requiring infrastructure management. You can access models from multiple model providers, integrate models into your applications, and scale usage based on workload requirements. With Amazon Bedrock, customer data is never used to train the underlying models. With the addition of Qwen3 models, Amazon Bedrock offers even more options for use cases like:

  • Code generation and repository analysis with extended context understanding
  • Building agentic workflows that orchestrate multiple tools and APIs for business automation
  • Balancing AI costs and performance using hybrid thinking modes for adaptive reasoning

Qwen3 models in Amazon Bedrock
These four Qwen3 models are now available in Amazon Bedrock, each optimized for different performance and cost requirements:

  • Qwen3-Coder-480B-A35B-Instruct – This is a mixture-of-experts (MoE) model with 480B total parameters and 35B active parameters. It’s optimized for coding and agentic tasks and achieves strong results in benchmarks such as agentic coding, browser use, and tool use. These capabilities make it suitable for repository-scale code analysis and multistep workflow automation.
  • Qwen3-Coder-30B-A3B-Instruct – This is a MoE model with 30B total parameters and 3B active parameters. Specifically optimized for coding tasks and instruction-following scenarios, this model demonstrates strong performance in code generation, analysis, and debugging across multiple programming languages.
  • Qwen3-235B-A22B-Instruct-2507 – This is an instruction-tuned MoE model with 235B total parameters and 22B active parameters. It delivers competitive performance across coding, math, and general reasoning tasks, balancing capability with efficiency.
  • Qwen3-32B (Dense) – This is a dense model with 32B parameters. It is suitable for real-time or resource-constrained environments such as mobile devices and edge computing deployments where consistent performance is critical.

Architectural and functional features in Qwen3
The Qwen3 models introduce several architectural and functional features:

MoE compared with dense architectures – MoE models such as Qwen3-Coder-480B-A35B, Qwen3-Coder-30B-A3B-Instruct, and Qwen3-235B-A22B-Instruct-2507, activate only part of the parameters for each request, providing high performance with efficient inference. The dense Qwen3-32B activates all parameters, offering more consistent and predictable performance.

Agentic capabilities – Qwen3 models can handle multi-step reasoning and structured planning in one model invocation. They can generate outputs that call external tools or APIs when integrated into an agent framework. The models also maintain extended context across long sessions. In addition, they support tool calling to allow standardized communication with external environments.

Hybrid thinking modes – Qwen3 introduces a hybrid approach to problem-solving, which supports two modes: thinking and non-thinking. The thinking mode applies step-by-step reasoning before delivering the final answer. This is ideal for complex problems that require deeper thought. Whereas the non-thinking mode provides fast and near-instant responses for less complex tasks where speed is more important than depth. This helps developers manage performance and cost trade-offs more effectively.

Long-context handling – The Qwen3-Coder models support extended context windows, with up to 256K tokens natively and up to 1 million tokens with extrapolation methods. This allows the model to process entire repositories, large technical documents, or long conversational histories within a single task.

When to use each model
The four Qwen3 models serve distinct use cases. Qwen3-Coder-480B-A35B-Instruct is designed for complex software engineering scenarios. It’s suited for advanced code generation, long-context processing such as repository-level analysis, and integration with external tools. Qwen3-Coder-30B-A3B-Instruct is particularly effective for tasks such as code completion, refactoring, and answering programming-related queries. If you need versatile performance across multiple domains, Qwen3-235B-A22B-Instruct-2507 offers a balance, delivering strong general-purpose reasoning and instruction-following capabilities while leveraging the efficiency advantages of its MoE architecture. Qwen3-32B (Dense) is appropriate for scenarios where consistent performance, low latency, and cost optimization are important.

Getting started with Qwen models in Amazon Bedrock
To begin using Qwen models, in the Amazon Bedrock console, I choose Model Access from the Configure and learn section of the navigation pane. I then navigate to the Qwen models to request access. In the Chat/Text Playground section of the navigation pane, I can quickly test the new Qwen models with my prompts.

To integrate Qwen3 models into my applications, I can use any AWS SDKs. The AWS SDKs include access to the Amazon Bedrock InvokeModel and Converse API. I can also use these model with any agentic framework that supports Amazon Bedrock and deploy the agents using Amazon Bedrock AgentCore. For example, here’s the Python code of a simple agent with tool access built using Strands Agents:

from strands import Agent
from strands_tools import calculator

agent = Agent(
    model="qwen.qwen3-coder-480b-instruct-v1:0",
    tools=[calculator]
)

agent("Tell me the square root of 42 ^ 9")

with open("function.py", 'r') as f:
    my_function_code = f.read()

agent(f"Help me optimize this Python function for better performance:\n\n{my_function_code}")

Now available
Qwen models are available today in the following AWS Regions:

  • Qwen3-Coder-480B-A35B-Instruct is available in the US West (Oregon), Asia Pacific (Mumbai, Tokyo), and Europe (London, Stockholm) Regions.
  • Qwen3-Coder-30B-A3B-Instruct, Qwen3-235B-A22B-Instruct-2507, and Qwen3-32B are available in the US East (N. Virginia), US West (Oregon), Asia Pacific (Mumbai, Tokyo), Europe (Ireland, London, Milan, Stockholm), and South America (São Paulo) Regions.

Check the full Region list for future updates. You can start testing and building immediately without infrastructure setup or capacity planning. To learn more, visit the Qwen in Amazon Bedrock product page and the Amazon Bedrock pricing page.

Try Qwen models on the Amazon Bedrock console now, and offer feedback through AWS re:Post for Amazon Bedrock or your typical AWS Support channels.

— Danilo

DeepSeek-V3.1 model now available in Amazon Bedrock

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/deepseek-v3-1-now-available-in-amazon-bedrock/

In March, Amazon Web Services (AWS) became the first cloud service provider to deliver DeepSeek-R1 in a serverless way by launching it as a fully managed, generally available model in Amazon Bedrock. Since then, customers have used DeepSeek-R1’s capabilities through Amazon Bedrock to build generative AI applications, benefiting from the Bedrock’s robust guardrails and comprehensive tooling for safe AI deployment.

Today, I am excited to announce DeepSeek-V3.1 is now available as a fully managed foundation model in Amazon Bedrock. DeepSeek-V3.1 is a hybrid open weight model that switches between thinking mode (chain-of-thought reasoning) for detailed step-by-step analysis and non-thinking mode (direct answers) for faster responses.

According to DeepSeek, the thinking mode of DeepSeek-V3.1 achieves comparable answer quality with better results, stronger multi-step reasoning for complex search tasks, and big gains in thinking efficiency compared with DeepSeek-R1-0528.

Benchmarks DeepSeek-V3.1 DeepSeek-R1-0528
Browsecomp 30.0 8.9
Browsecomp_zh 49.2 35.7
HLE 29.8 24.8
xbench-DeepSearch 71.2 55.0
Frames 83.7 82.0
SimpleQA 93.4 92.3
Seal0 42.6 29.7
SWE-bench Verified 66.0 44.6
SWE-bench Multilingual 54.5 30.5
Terminal-Bench 31.3 5.7
(c)
https://api-docs.deepseek.com/news/news250821

DeepSeek-V3.1 model performance in tool usage and agent tasks has significantly improved through post-training optimization compared to previous DeepSeek models. DeepSeek-V3.1 also supports over 100 languages with near-native proficiency, including significantly improved capability in low-resource languages lacking large monolingual or parallel corpora. You can build global applications to deliver enhanced accuracy and reduced hallucinations compared to previous DeepSeek models, while maintaining visibility into its decision-making process.

Here are your key use cases using this model:

  • Code generation – DeepSeek-V3.1 excels in coding tasks with improvements in software engineering benchmarks and code agent capabilities, making it ideal for automated code generation, debugging, and software engineering workflows. It performs well on coding benchmarks while delivering high-quality results efficiently.
  • Agentic AI tools – The model features enhanced tool calling through post-training optimization, making it strong in tool usage and agentic workflows. It supports structured tool calling, code agents, and search agents, positioning it as a solid choice for building autonomous AI systems.
  • Enterprise applications – DeepSeek models are integrated into various chat platforms and productivity tools, enhancing user interactions and supporting customer service workflows. The model’s multilingual capabilities and cultural sensitivity make it suitable for global enterprise applications.

As I mentioned in my previous post, when implementing publicly available models, give careful consideration to data privacy requirements when implementing in your production environments, check for bias in output, and monitor your results in terms of data security, responsible AI, and model evaluation.

You can access the enterprise-grade security features of Amazon Bedrock and implement safeguards customized to your application requirements and responsible AI policies with Amazon Bedrock Guardrails. You can also evaluate and compare models to identify the optimal model for your use cases by using Amazon Bedrock model evaluation tools.

Get started with the DeepSeek-V3.1 model in Amazon Bedrock
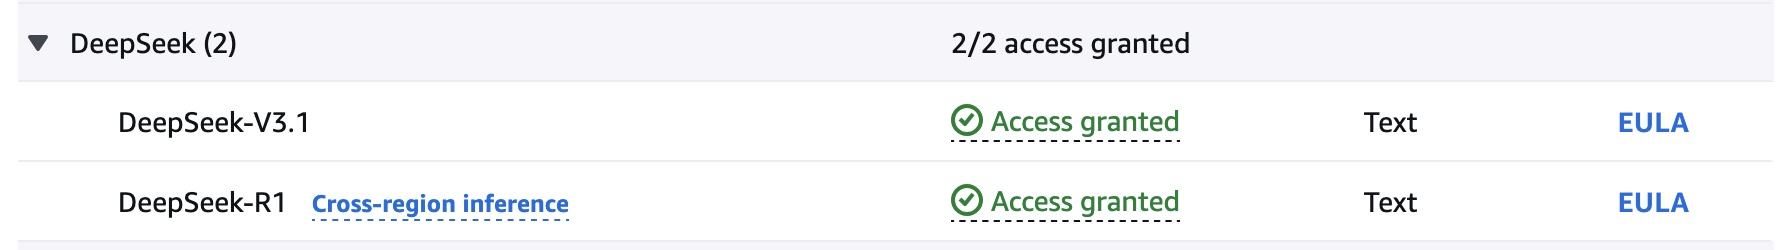
If you’re new to using the DeepSeek-V3.1 model, go to the Amazon Bedrock console, choose Model access under Bedrock configurations in the left navigation pane. To access the fully managed DeepSeek-V3.1 model, request access for DeepSeek-V3.1 in the DeepSeek section. You’ll then be granted access to the model in Amazon Bedrock.

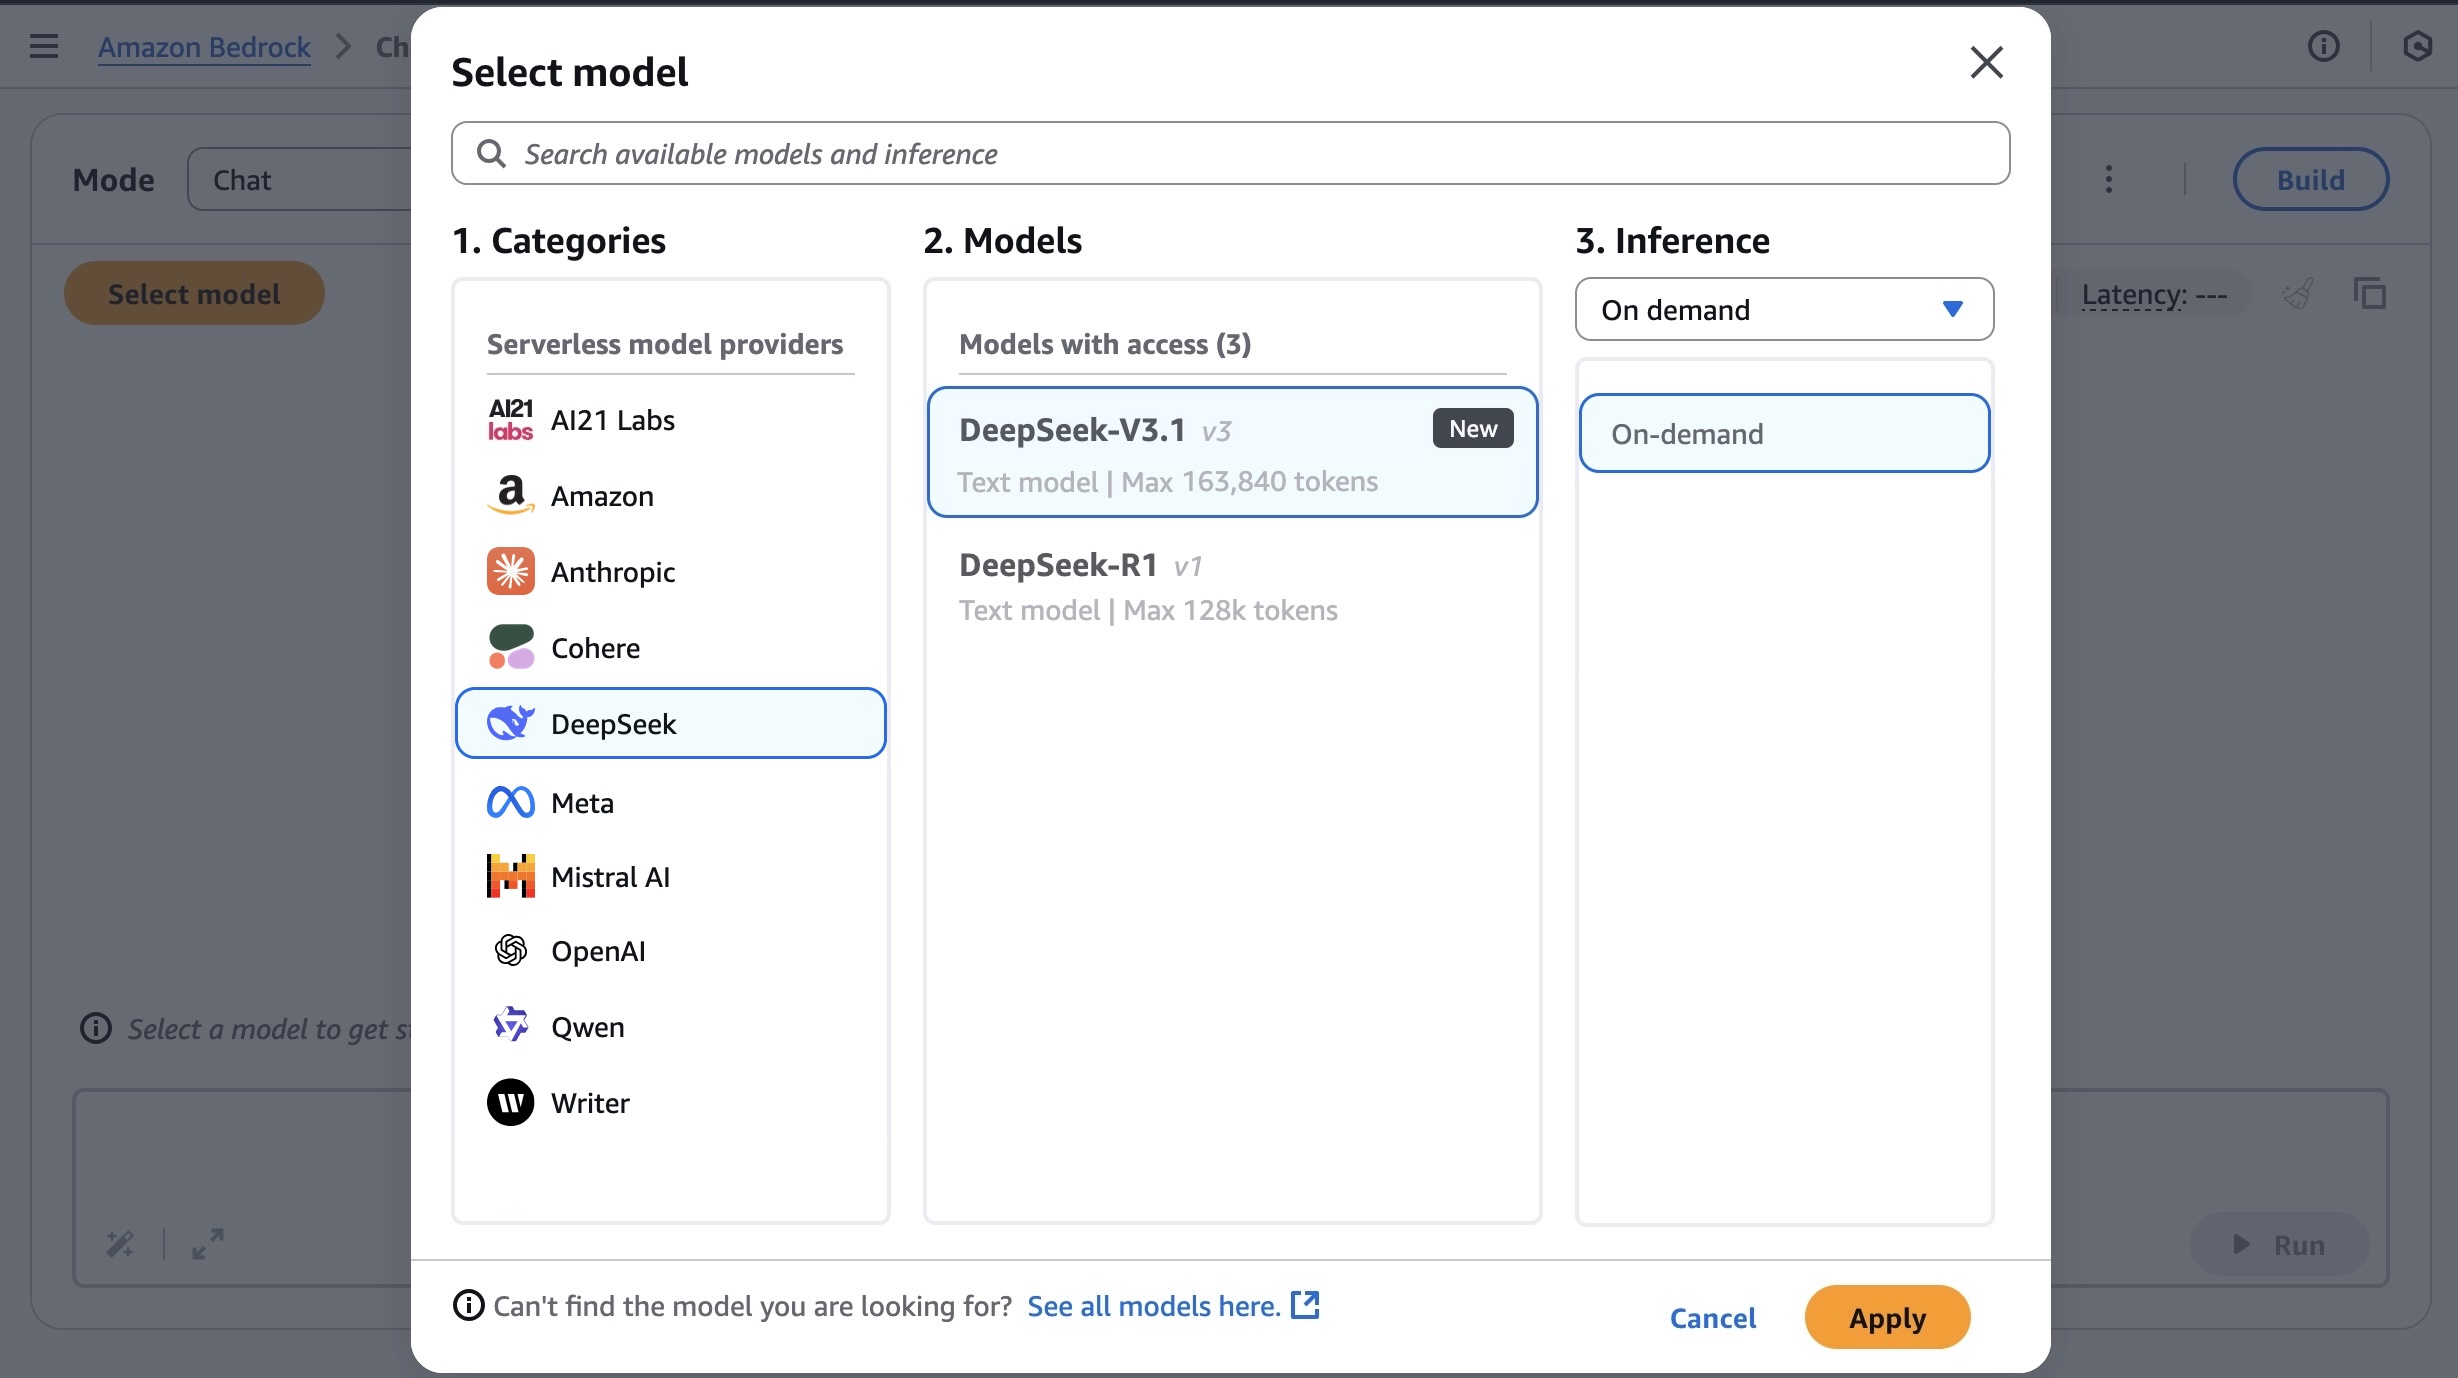
Next, to test the DeepSeek-V3.1 model in Amazon Bedrock, choose Chat/Text under Playgrounds in the left menu pane. Then choose Select model in the upper left, and select DeepSeek as the category and DeepSeek-V3.1 as the model. Then choose Apply.

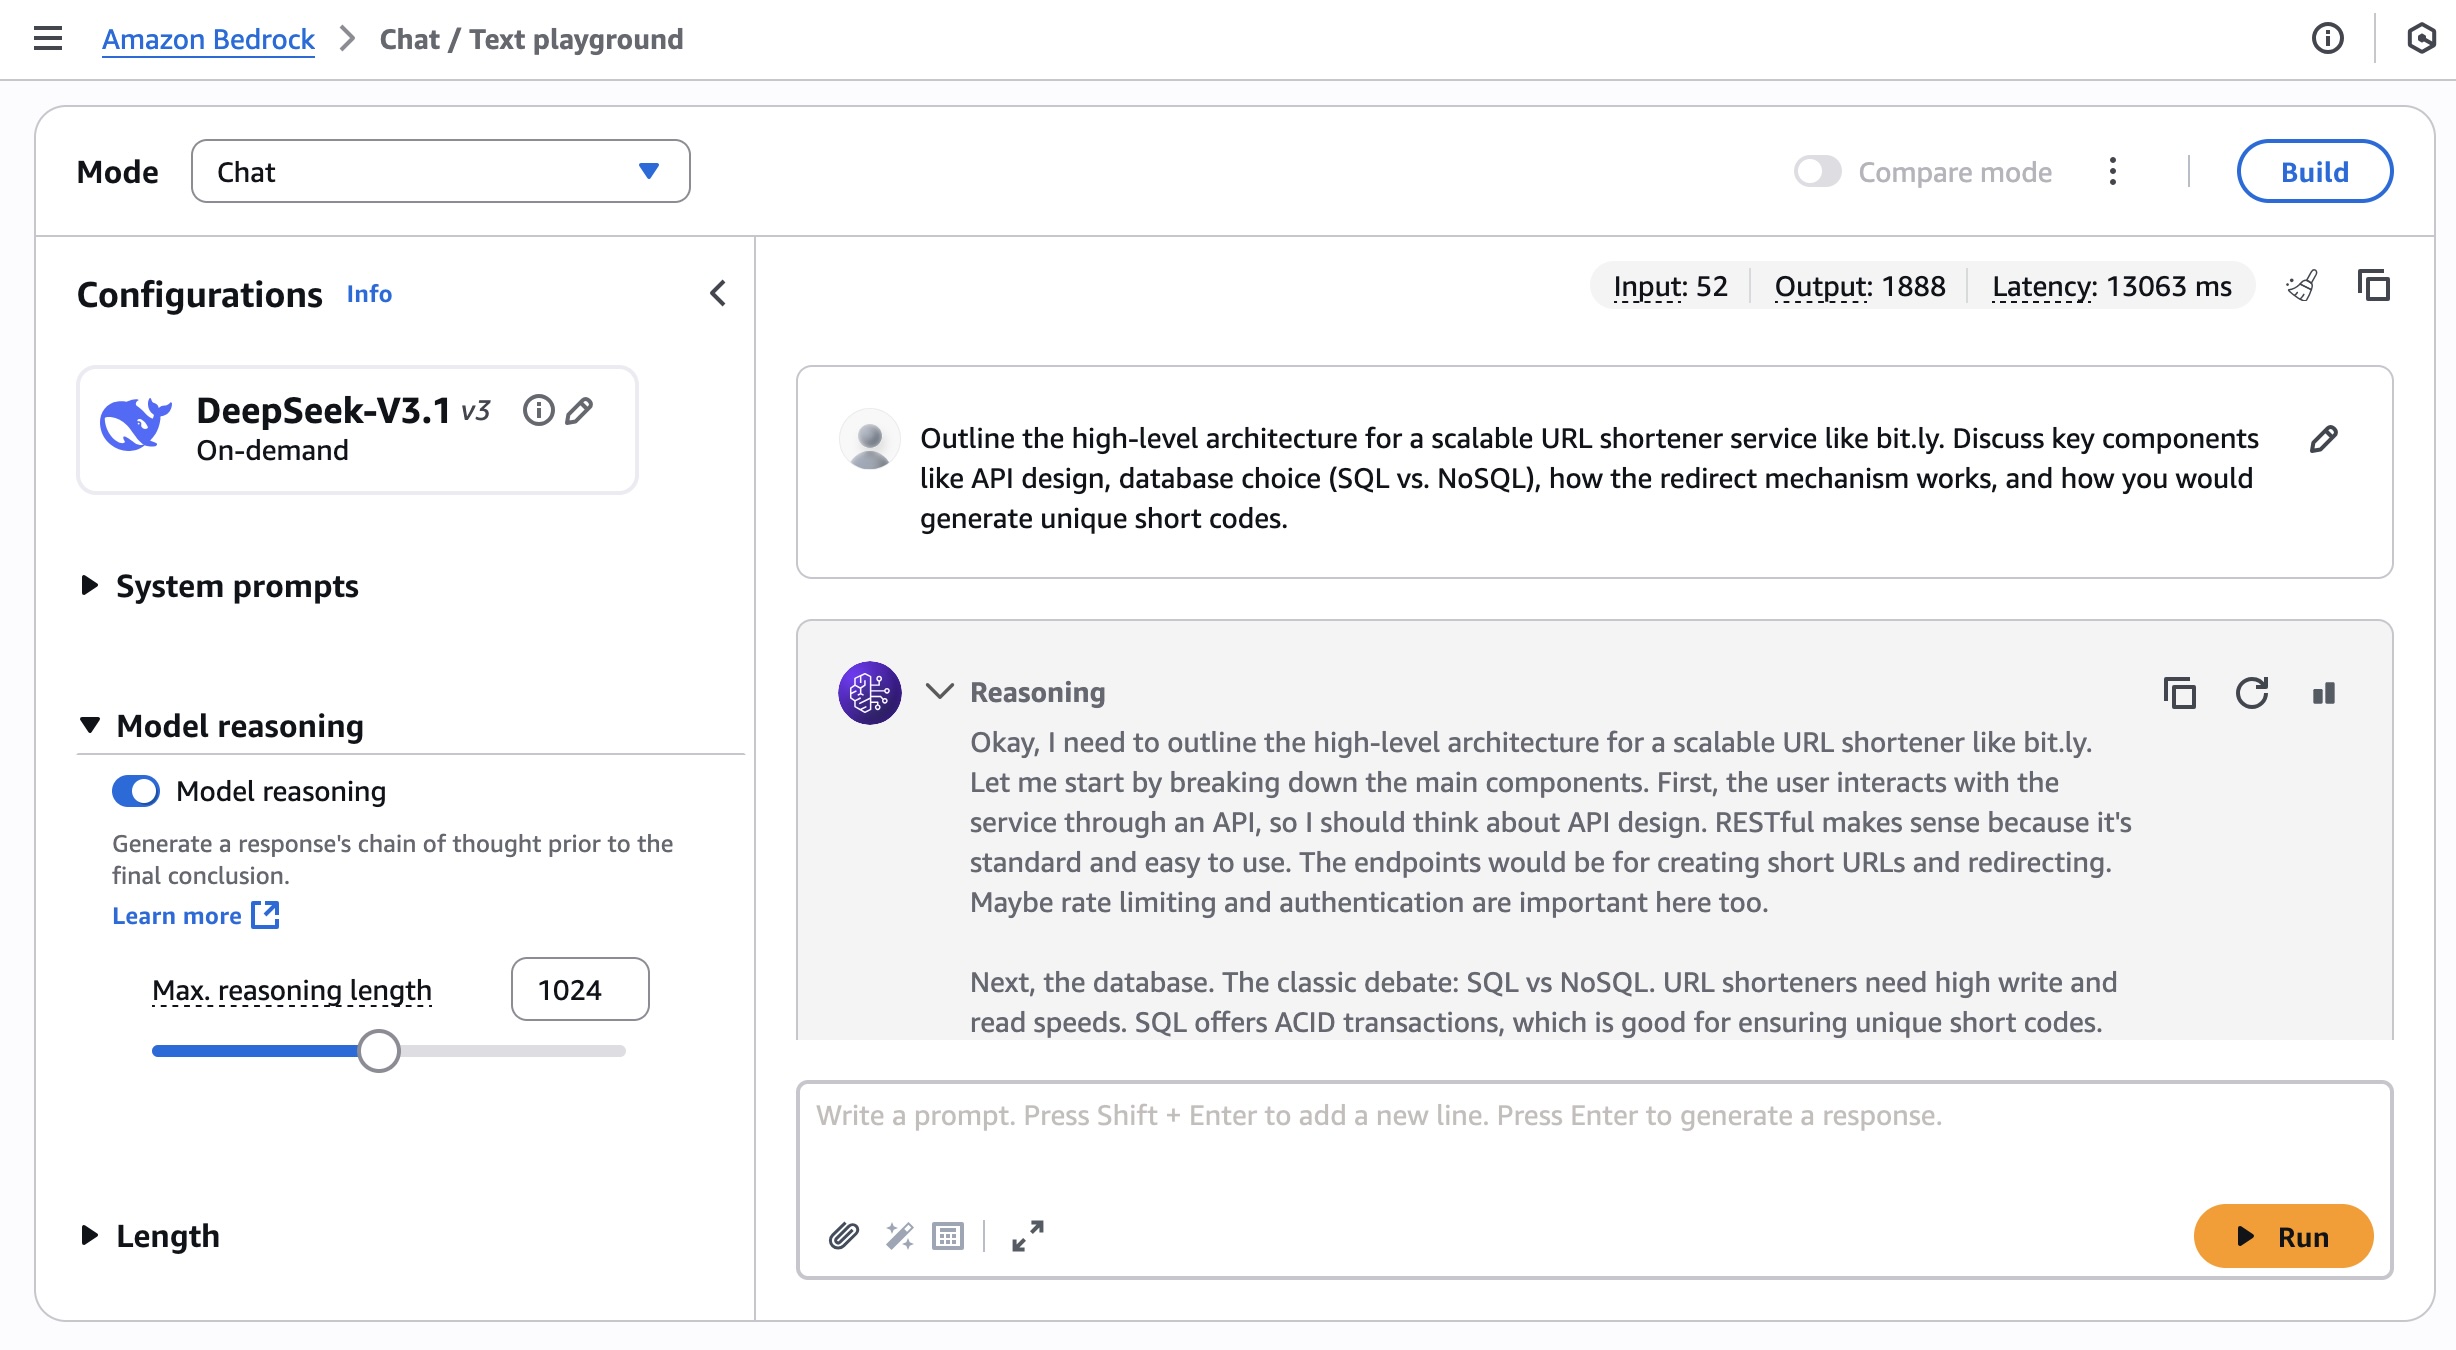
Using the selected DeepSeek-V3.1 model, I run the following prompt example about technical architecture decision.

Outline the high-level architecture for a scalable URL shortener service like bit.ly. Discuss key components like API design, database choice (SQL vs. NoSQL), how the redirect mechanism works, and how you would generate unique short codes.

You can turn the thinking on and off by toggling Model reasoning mode to generate a response’s chain of thought prior to the final conclusion.

You can also access the model using the AWS Command Line Interface (AWS CLI) and AWS SDK. This model supports both the InvokeModel and Converse API. You can check out a broad range of code examples for multiple use cases and a variety of programming languages.

To learn more, visit DeepSeek model inference parameters and responses in the AWS documentation.

Now available
DeepSeek-V3.1 is now available in the US West (Oregon), Asia Pacific (Tokyo), Asia Pacific (Mumbai), Europe (London), and Europe (Stockholm) AWS Regions. Check the full Region list for future updates. To learn more, check out the DeepSeek in Amazon Bedrock product page and the Amazon Bedrock pricing page.

Give the DeepSeek-V3.1 model a try in the Amazon Bedrock console today and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

— Channy

Accelerate serverless testing with LocalStack integration in VS Code IDE

Post Syndicated from Micah Walter original https://aws.amazon.com/blogs/aws/accelerate-serverless-testing-with-localstack-integration-in-vs-code-ide/

Today, we’re announcing LocalStack integration in the AWS Toolkit for Visual Studio Code that makes it easier than ever for developers to test and debug serverless applications locally. This enhancement builds upon our recent improvements to the AWS Lambda development experience, including the console to IDE integration and remote debugging capabilities we launched in July 2025, continuing our commitment to simplify serverless development on Amazon Web Services (AWS).

When building serverless applications, developers typically focus on three key areas to streamline their testing experience: unit testing, integration testing, and debugging resources running in the cloud. Although AWS Serverless Application Model Command Line Interface (AWS SAM CLI) provides excellent local unit testing capabilities for individual Lambda functions, developers working with event-driven architectures that involve multiple AWS services, such as Amazon Simple Queue Service (Amazon SQS), Amazon EventBridge, and Amazon DynamoDB, need a comprehensive solution for local integration testing. Although LocalStack provided local emulation of AWS services, developers had to previously manage it as a standalone tool, requiring complex configuration and frequent context switching between multiple interfaces, which slowed down the development cycle.

LocalStack integration in AWS Toolkit for VS Code
To address these challenges, we’re introducing LocalStack integration so developers can connect AWS Toolkit for VS Code directly to LocalStack endpoints. With this integration, developers can test and debug serverless applications without switching between tools or managing complex LocalStack setups. Developers can now emulate end-to-end event-driven workflows involving services such as Lambda, Amazon SQS, and EventBridge locally, without needing to manage multiple tools, perform complex endpoint configurations, or deal with service boundary issues that previously required connecting to cloud resources.

The key benefit of this integration is that AWS Toolkit for VS Code can now connect to custom endpoints such as LocalStack, something that wasn’t possible before. Previously, to point AWS Toolkit for VS Code to their LocalStack environment, developers had to perform manual configuration and context switching between tools.

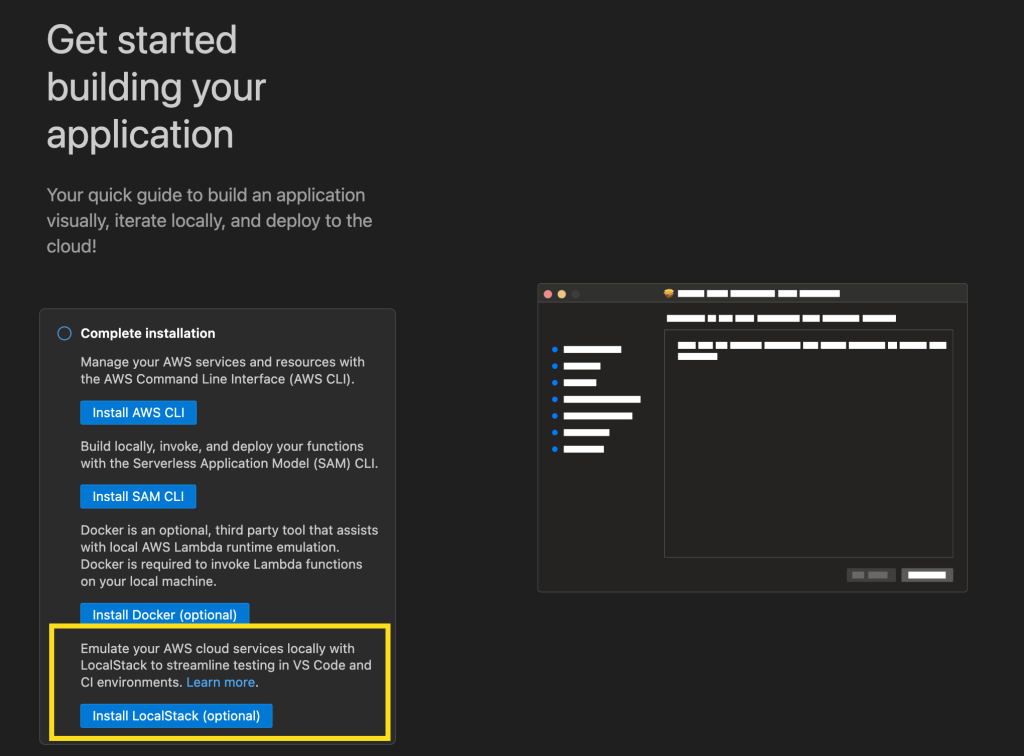
Getting started with LocalStack in VS Code is straightforward. Developers can begin with the LocalStack Free version, which provides local emulation for core AWS services ideal for early-stage development and testing. Using the guided application walkthrough in VS Code, developers can install LocalStack directly from the toolkit interface, which automatically installs the LocalStack extension and guides them through the setup process. When it’s configured, developers can deploy serverless applications directly to the emulated environment and test their functions locally, all without leaving their IDE.

Let’s try it out
First, I’ll update my copy of the AWS Toolkit for VS Code to the latest version. Once, I’ve done this, I can see a new option when I go to Application Builder and click on Walkthrough of Application Builder. This allows me to install LocalStack with a single click.

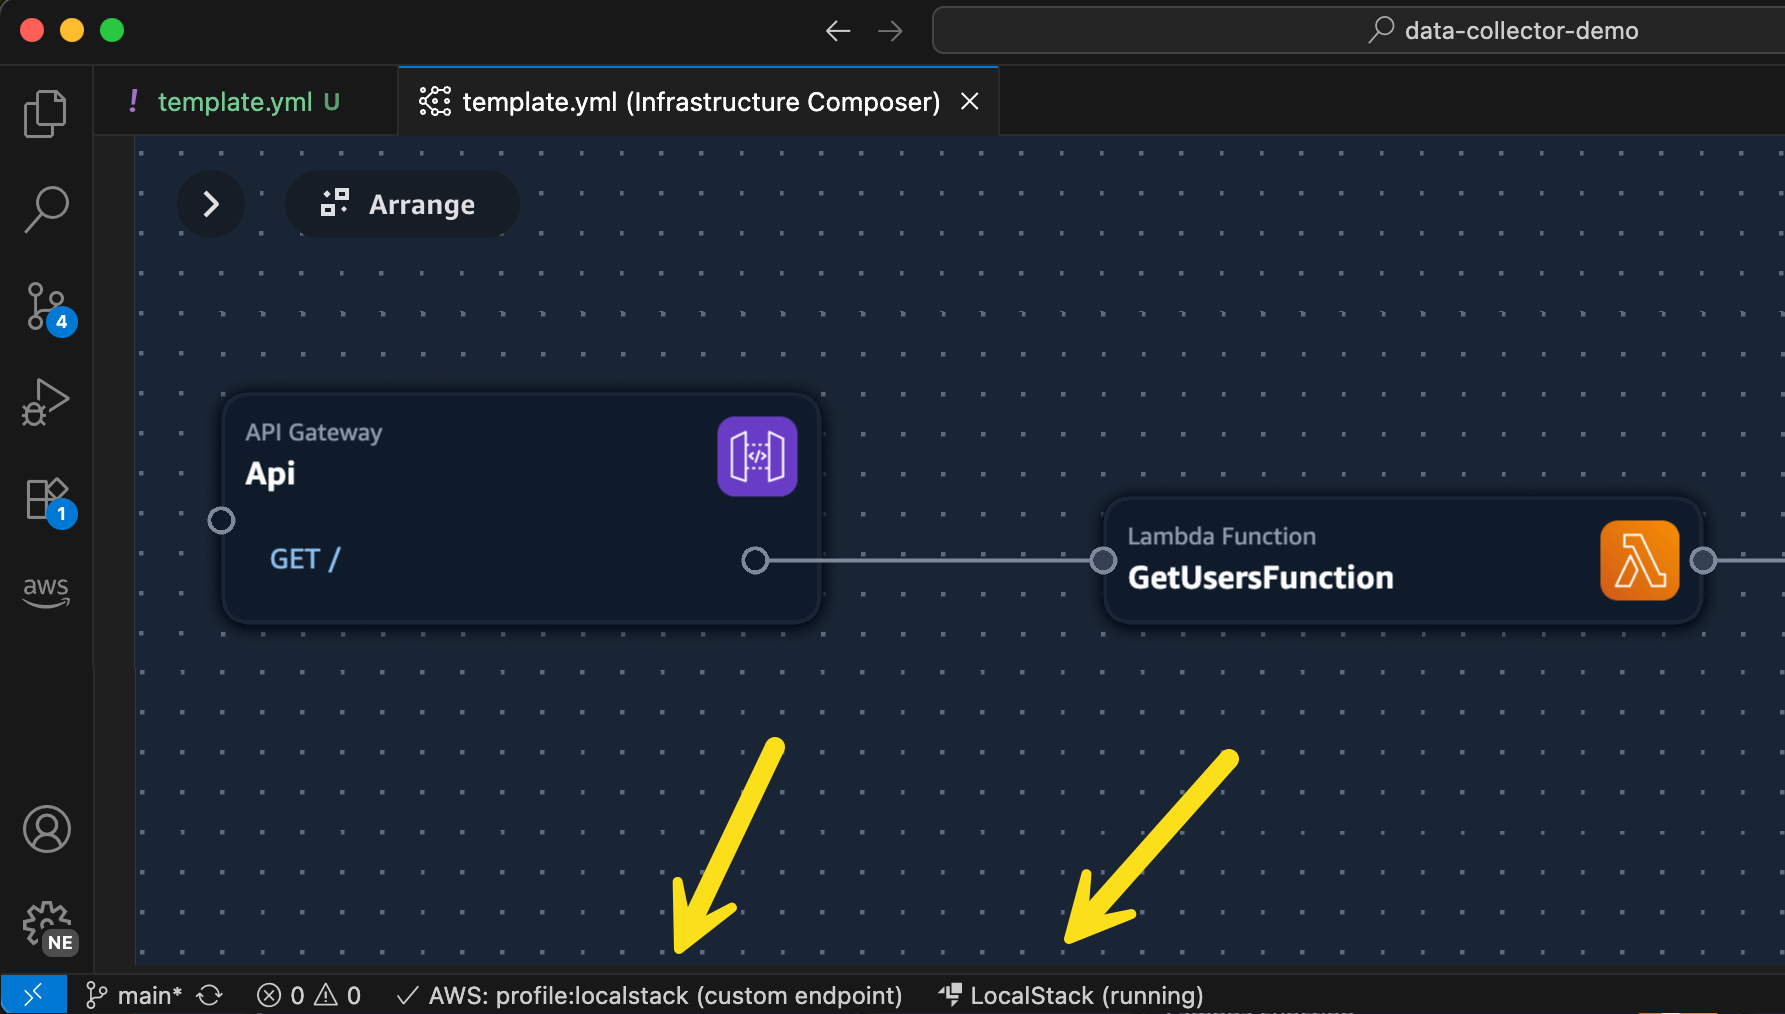
Once I’ve completed the setup for LocalStack, I can start it up from the status bar and then I’ll be able to select LocalStack from the list of my configured AWS profiles. In this illustration, I am using Application Composer to build a simple serverless architecture using Amazon API Gateway, Lambda, and DynamoDB. Normally, I’d deploy this to AWS using AWS SAM. In this case, I’m going to use the same AWS SAM command to deploy my stack locally.

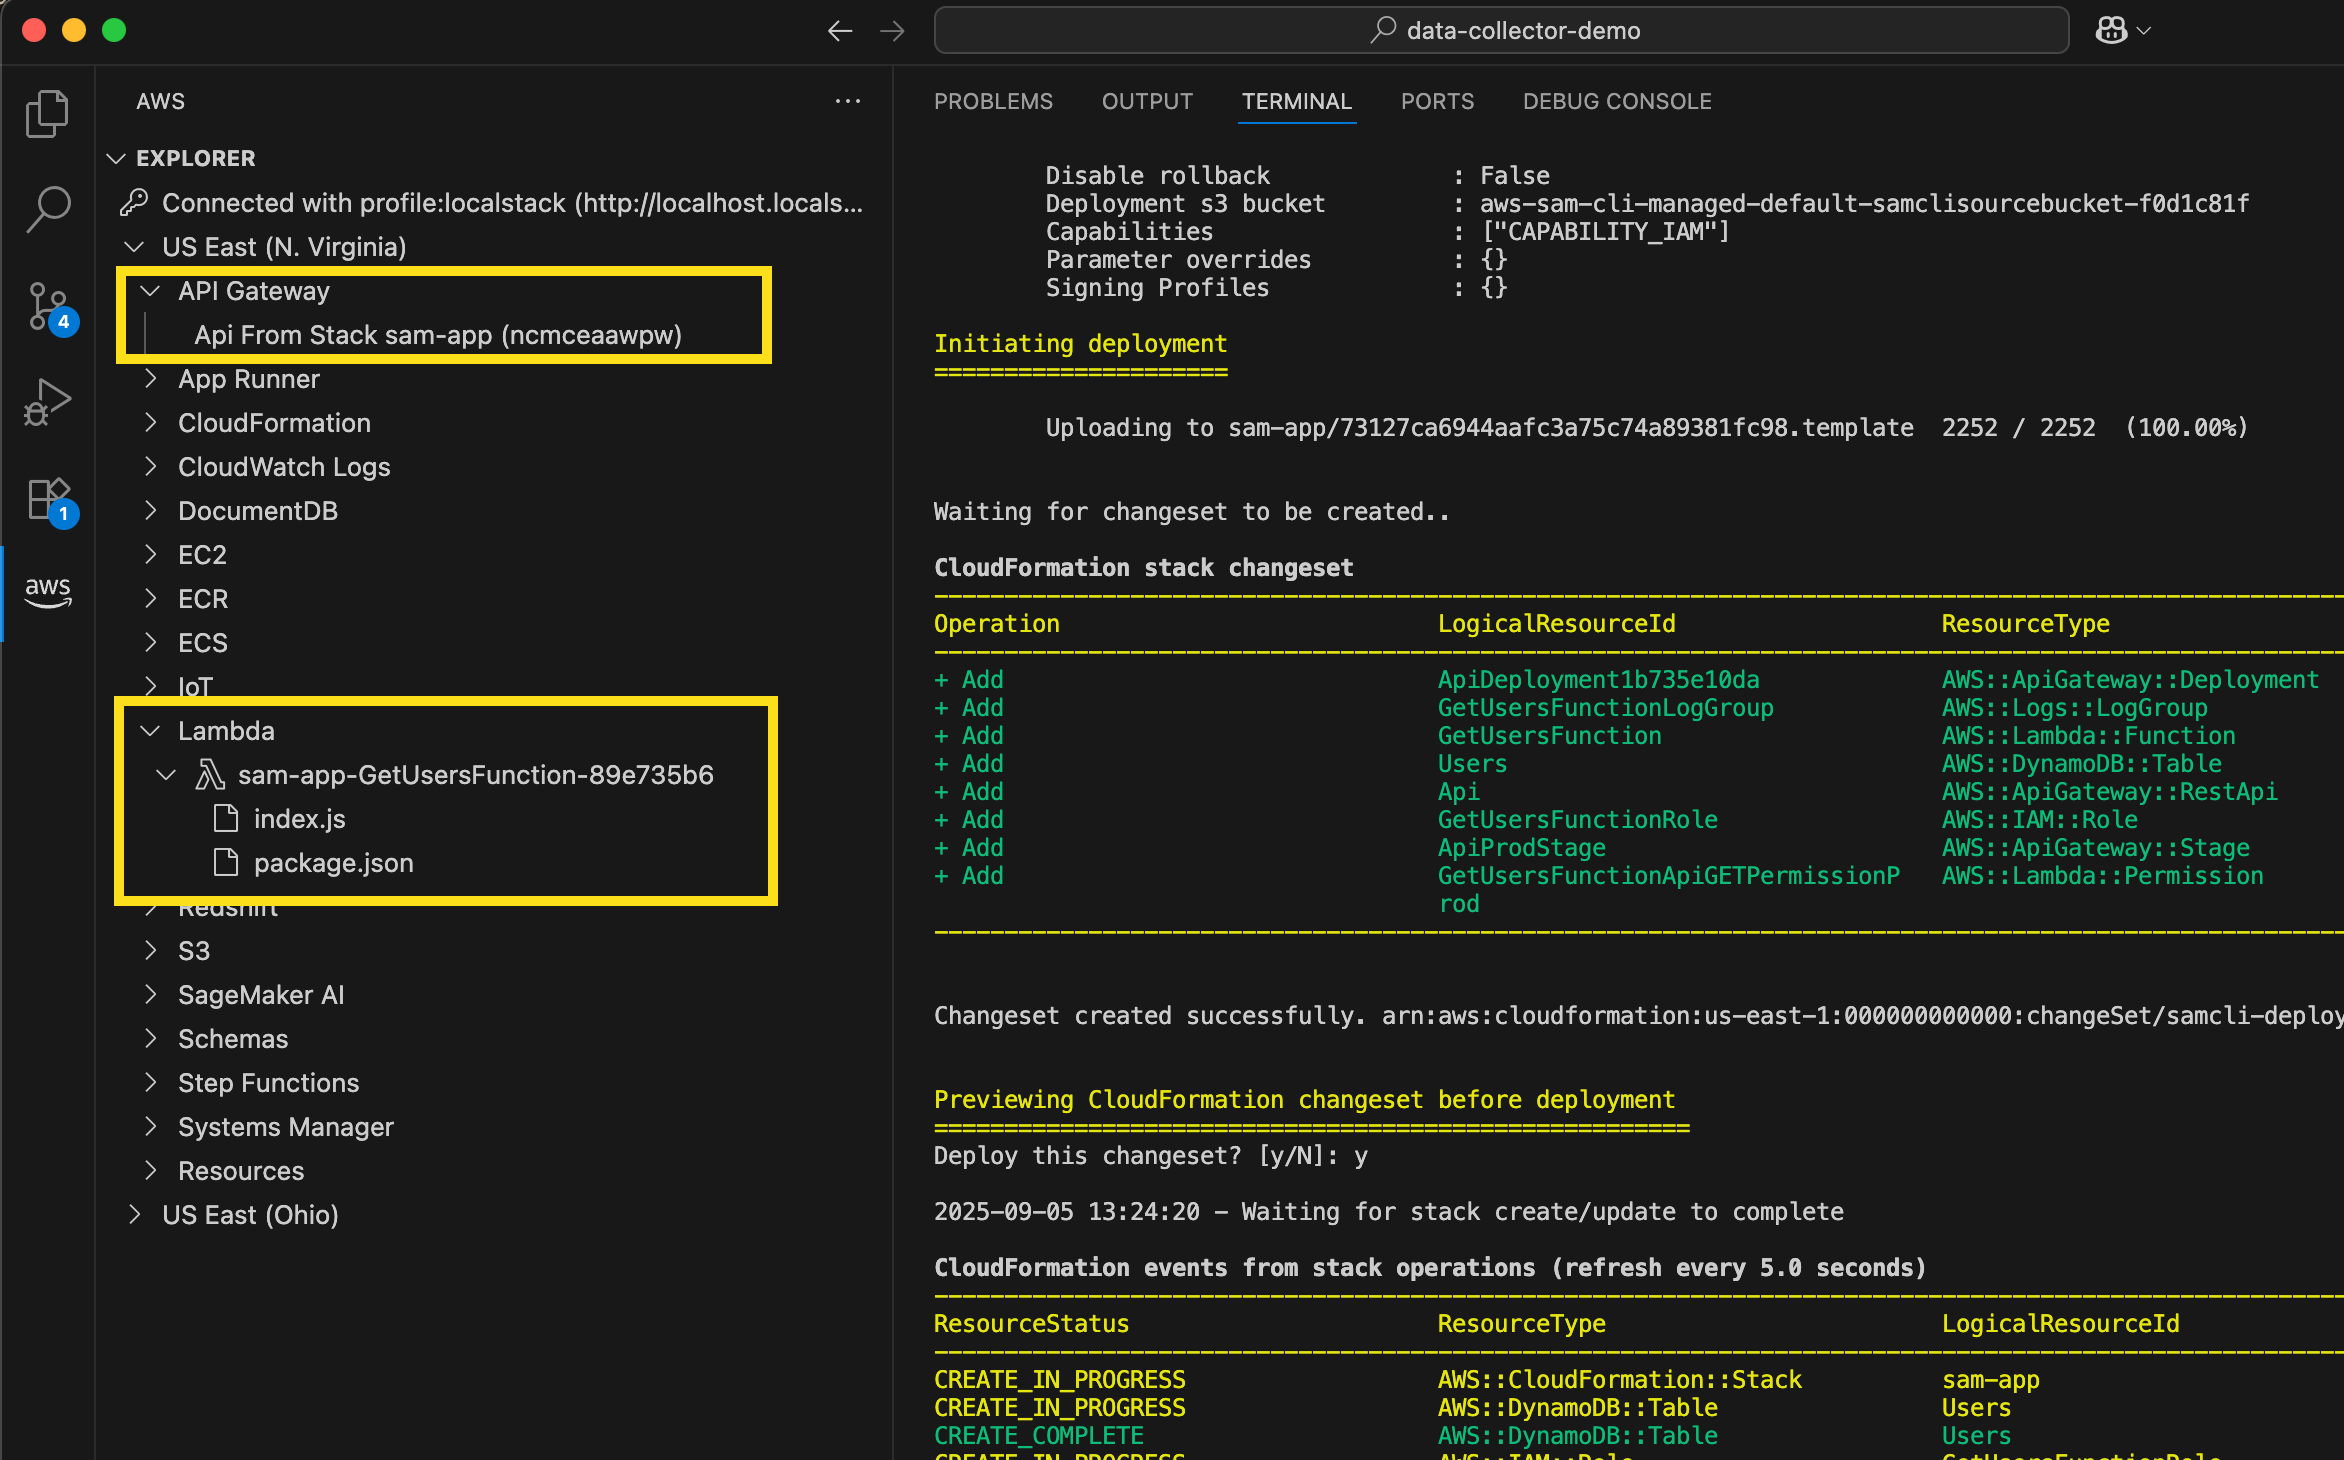
I just do `sam deploy –guided –profile localstack` from the command line and follow the usual prompts. Deploying to LocalStack using AWS SAM CLI provides the exact same experience I’m used to when deploying to AWS. In the screenshot below, I can see the standard output from AWS SAM, as well as my new LocalStack resources listed in the AWS Toolkit Explorer.

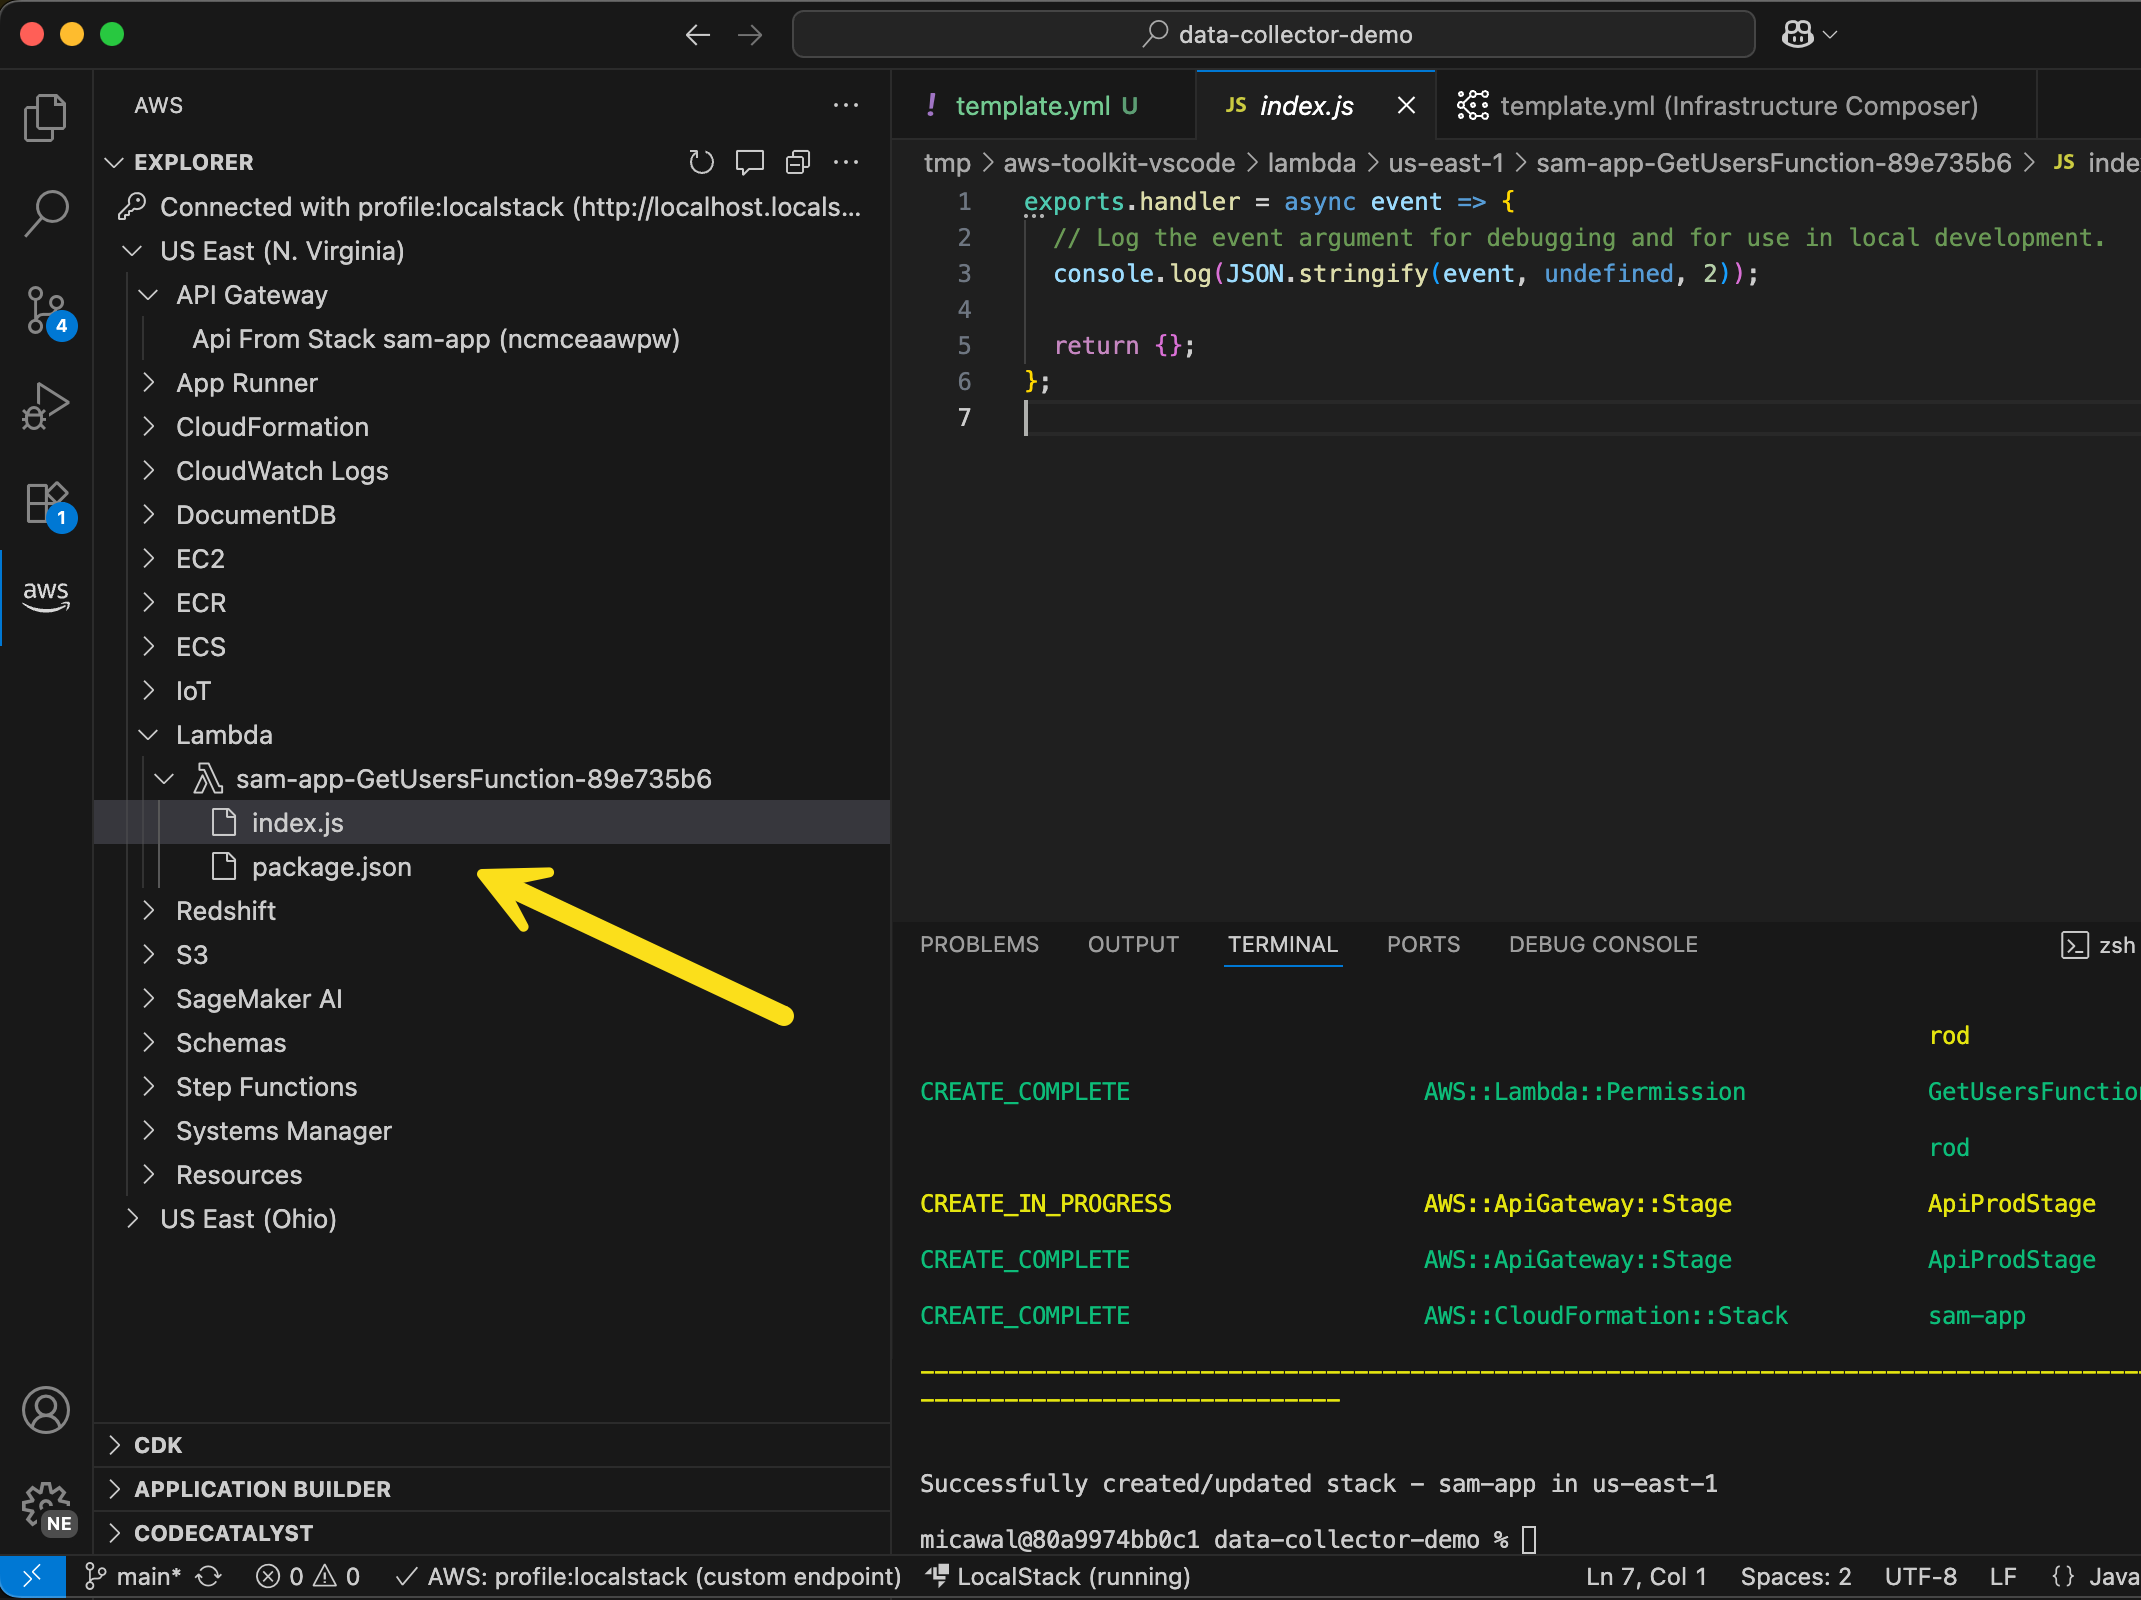
I can even go in to a Lambda function and edit the function code I’ve deployed locally!

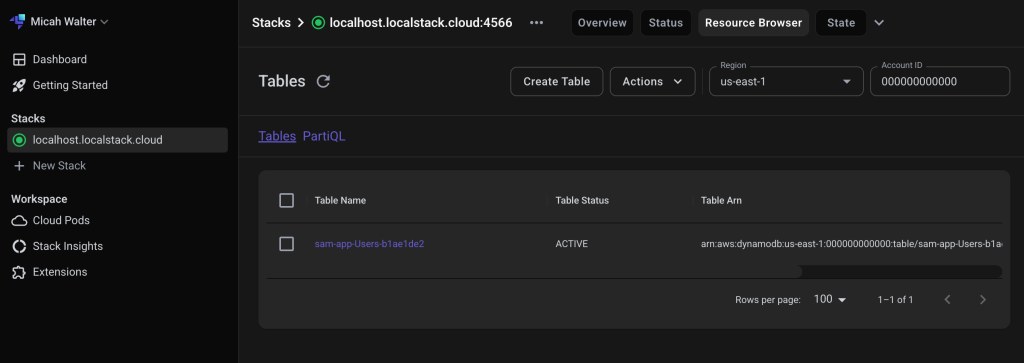
Over on the LocalStack website, I can login and take a look at all the resources I have running locally. In the screenshot below, you can see the local DynamoDB table I just deployed.

Enhanced development workflow
These new capabilities complement our recently launched console-to-IDE integration and remote debugging features, creating a comprehensive development experience that addresses different testing needs throughout the development lifecycle. AWS SAM CLI provides excellent local testing for individual Lambda functions, handling unit testing scenarios effectively. For integration testing, the LocalStack integration enables testing of multiservice workflows locally without the complexity of AWS Identity and Access Management (IAM) permissions, Amazon Virtual Private Cloud (Amazon VPC) configurations, or service boundary issues that can slow down development velocity.

When developers need to test using AWS services in development environments, they can use our remote debugging capabilities, which provide full access to Amazon VPC resources and IAM roles. This tiered approach frees up developers to focus on business logic during early development phases using LocalStack, then seamlessly transition to cloud-based testing when they need to validate against AWS service behaviors and configurations. The integration eliminates the need to switch between multiple tools and environments, so developers can identify and fix issues faster while maintaining the flexibility to choose the right testing approach for their specific needs.

Now available
You can start using these new features through the AWS Toolkit for VS Code by updating to v3.74.0. The LocalStack integration is available in all commercial AWS Regions except AWS GovCloud (US) Regions. To learn more, visit the AWS Toolkit for VS Code and Lambda documentation.

For developers who need broader service coverage or advanced capabilities, LocalStack offers additional tiers with expanded features. There are no additional costs from AWS for using this integration.

These enhancements represent another significant step forward in our ongoing commitment to simplifying the serverless development experience. Over the past year, we’ve focused on making VS Code the tool of choice for serverless developers, and this LocalStack integration continues that journey by providing tools for developers to build and test serverless applications more efficiently than ever before.

Accessing private Amazon API Gateway endpoints through custom Amazon CloudFront distribution using VPC Origins

Post Syndicated from Napoleone Capasso original https://aws.amazon.com/blogs/compute/accessing-private-amazon-api-gateway-endpoints-through-custom-amazon-cloudfront-distribution-using-vpc-origins/

Organizations can use Amazon CloudFront Virtual Private Cloud (VPC) Origins to deliver content from applications hosted in private subnets within Amazon VPC. Network traffic flows between Amazon CloudFront and Application Load Balancers (ALBs), Network Load Balancers (NLBs), or Amazon Elastic Compute Cloud (Amazon EC2) instances deployed within private subnets. This means that Amazon CloudFront can access both public and private Amazon Web Services (AWS) resources seamlessly.

This post demonstrates how you can connect CloudFront with a Private REST API in Amazon REST API Gateway using a VPC origin.

Overview

Organizations looking to enhance their application security and performance can find several key benefits in this architecture. You can use it to keep your APIs private and access them through CloudFront, implementing more security layers such as AWS Shield Advanced, geoblocking and TLSv1.3 support along with custom cipher suites. You can use this approach to engage the global CloudFront content delivery network while maintaining more control over the distribution.

Furthermore, you can enhance security controls through the built-in features of CloudFront, such as AWS WAF integration, custom SSL certificates, and field-level encryption. The VPC Origins feature eliminates any need to expose your internal resources to the public internet, which reduces your application’s potential attack surface.

Enterprises that need to maintain strict compliance requirements while delivering content globally can find this solution particularly valuable. Contain all traffic within the AWS private network to better meet your security and compliance objectives while still providing fast, reliable access to your applications.

Solution overview

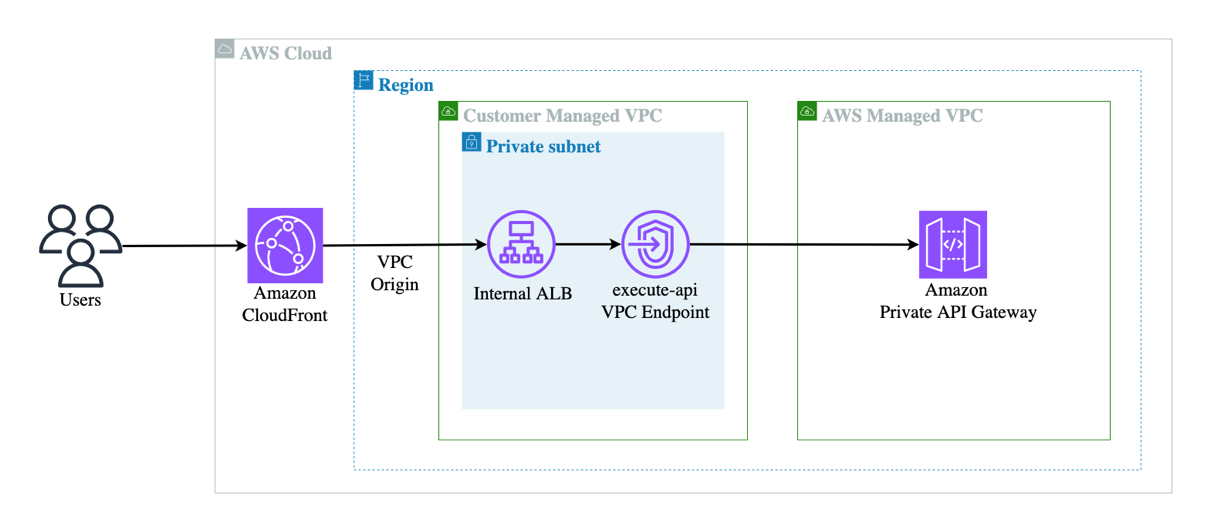
You can set up CloudFront as the front door to your application and use VPC Origins integrated with an internal ALB to route traffic to Private Rest API through an execute-api VPC endpoint. All traffic between CloudFront and Private REST API remains within the AWS Private network.

The following figure provides an overview of the solution.

Figure 1: Amazon CloudFront to Private Amazon API Gateway

This diagram depicts three services running in an AWS account. The CloudFront distribution serves as the main entry point for the application. This distribution connects to an internal ALB using VPC Origins. The interface VPC endpoint execute-api is set as the target for the internal ALB to route requests to the Private Amazon API Gateway.

Solution deployment

To deploy this solution, follow the instructions in the GitHub repository and clone the repository.

The solution can be deployed in any AWS Region. Make sure to have a valid SSL certificate in AWS Certificate Manager (ACM) in the us-east-1 Region for the CloudFront distribution. All other resources must be in the same Region.

Prerequisites

For this walkthrough, the following resources are needed:

  • An Amazon VPC with at least 2 Private Subnets.
  • A Public Hosted Zone in Amazon Route 53.
  • A valid public SSL certificate in ACM in the us-east-1 Region for CloudFront and another certificate in the same Region as an ALB.
  • A custom domain name, covered by the ACM certificate for CloudFront distribution.

These are the input parameters for the solution deployment.

Walkthrough

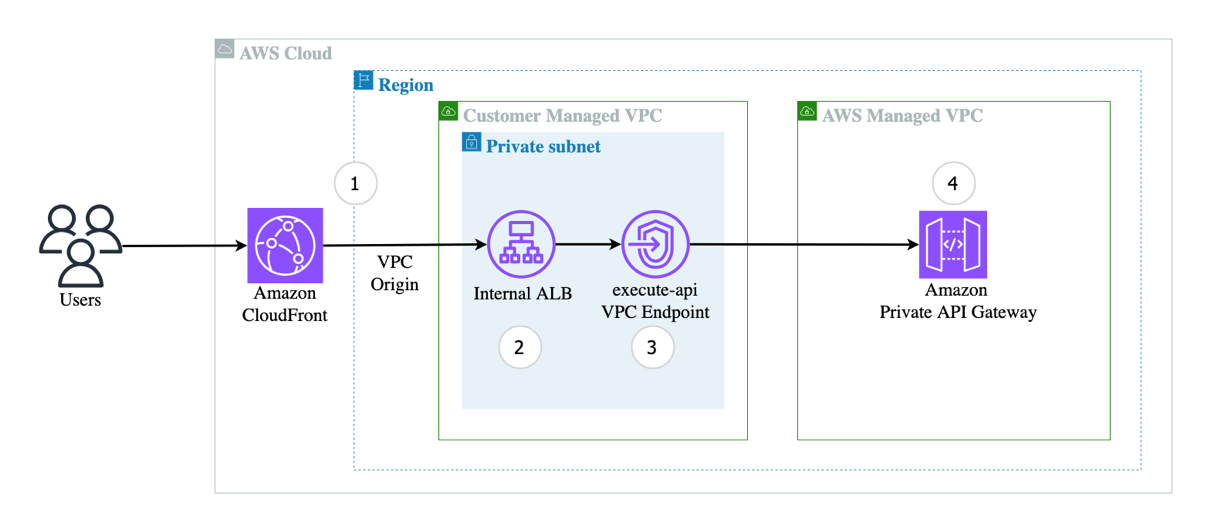
The AWS Serverless Application Model (AWS SAM) template from the sample GitHub repository creates a secure, private networking architecture that provides controlled access to an API Gateway through CloudFront. It provisions a private API Gateway with a VPC endpoint, an internal ALB, and a CloudFront distribution. The template establishes secure communication channels by implementing private networking components, configuring SSL certificates, and setting up Route53 DNS routing. It uses custom AWS Lambda resources to dynamically manage network interfaces and security group configurations, providing a robust and flexible infrastructure for private API access, as shown in the following figure.

Figure 2: Amazon CloudFront to Private Amazon API Gateway walkthrough

Step 1: Create the CloudFront distribution and the VPC Origins

The solution creates a CloudFront distribution that enables wide range of HTTP clients by supporting HTTP2 and HTTP3, enhances your solution security by enforcing HTTPS-only traffic, and uses a custom domain with the user-provided SSL certificate.The internal ALB is configured as the origin for the CloudFront distribution, and it is created using the VPC Origins feature.

########### Cloudfront Distribution ###############
  CloudFrontDistribution:
    Type: AWS::CloudFront::Distribution
    Properties:
      DistributionConfig:
        HttpVersion: http2and3
        Comment: CloudFront Distribution with VPC Origin Integration
        Aliases: 
        - !Ref CloudFrontDomainName
        ViewerCertificate:
          AcmCertificateArn: !Ref CloudFrontCertificateARN
          MinimumProtocolVersion: TLSv1.2_2021
          SslSupportMethod: sni-only
        Origins:
        - Id: AlbOrigin
          DomainName: !GetAtt ApplicationLoadBalancer.DNSName
          VpcOriginConfig:
            OriginKeepaliveTimeout: 60
            OriginReadTimeout: 60
            VpcOriginId: !GetAtt CloudFrontVpcOrigin.Id
        Enabled: true
        DefaultCacheBehavior:
          TargetOriginId: AlbOrigin
          CachePolicyId: 83da9c7e-98b4-4e11-a168-04f0df8e2c65
          OriginRequestPolicyId: 216adef6-5c7f-47e4-b989-5492eafa07d3
          ViewerProtocolPolicy: https-only

The VPC Origins references the internal ALB, and only supports HTTPS protocol.

  ########### Cloudfront VPC Origin ###############
  CloudFrontVpcOrigin:
    Type: AWS::CloudFront::VpcOrigin
    Properties:
      VpcOriginEndpointConfig:
          Arn: !Ref ApplicationLoadBalancer
          Name: !Sub vpc-origin-${AWS::StackName}
          OriginProtocolPolicy: https-only
          OriginSSLProtocols: 
          - TLSv1.2

When the VPC Origins is created, the custom resource Lambda function adds an inbound rule to the CloudFront VPC Origin security group to allow traffic only from the CloudFront prefix list in the chosen Region.

        ec2_client.authorize_security_group_ingress(
            GroupId=cloudfront_sg_id,
            IpPermissions=[
                {
                    'IpProtocol': 'tcp',  
                    'FromPort': 443,      
                    'ToPort': 443,        
                    'PrefixListIds': [{'PrefixListId': cloudfront_prefix_id}]
                }
            ]
        )

Step 2: Create the ALB

The internal ALB is configured with an HTTPS listener using the user-provided SSL certificate. This maintains the encryption of the traffic between CloudFront and the ALB.

########### ALB Listener ###########  
  ALBListener:
    Type: AWS::ElasticLoadBalancingV2::Listener
    Properties:
      DefaultActions:
        - Type: forward
          TargetGroupArn: !Ref ALBTargetGroup
      LoadBalancerArn: !Ref ApplicationLoadBalancer
      Port: '443'
      Protocol: HTTPS
      SslPolicy: ELBSecurityPolicy-TLS-1-2-2017-01
      Certificates:
        - CertificateArn: !Ref ALBCertificateARN

The target group of the ALB points to the execute API VPC endpoint IP addresses. These IP addresses are fetched using a custom resource Lambda function.

  ########### ALB Target Group ###########
  ALBTargetGroup:
    Type: AWS::ElasticLoadBalancingV2::TargetGroup
    Properties:
      Port: 443
      Name: !Sub TargetGroup-${AWS::StackName}
      Protocol: HTTPS
      VpcId: !Ref VPCId
      Targets:
        - Id: !GetAtt GetPrivateIPs.IP0
          Port: 443
        - Id: !GetAtt GetPrivateIPs.IP1
          Port: 443
      TargetType: ip
      Matcher:
        HttpCode: '200,403'

The custom resource Lambda function fetches private IPs for given network interface IDs using the EC2 client and returns a dictionary with keys IP0 and IP1 values as the private IPs.

def fetch_interface_ips(network_interface_ids):
    """
    Fetch private IPs for given network interface IDs using ec2 client
    Returns a dictionary with keys IP0, IP1, etc. and values as the private IPs
    """
    responseData = {}
    
    # Use describe_network_interfaces instead of the resource approach
    response = ec2_client.describe_network_interfaces(
        NetworkInterfaceIds=network_interface_ids
    )
    
    for index, interface in enumerate(response['NetworkInterfaces']):
        responseData[f'IP{index}'] = interface['PrivateIpAddress']
    
    return responseData

Furthermore, the Lambda function adds an inbound rule to the internal ALB security group to allow traffic from the VPC Origin security group.

ec2_client.authorize_security_group_ingress(
            GroupId=security_group_id,
            IpPermissions=[
                {
                    'IpProtocol': 'tcp',  
                    'FromPort': 443,     
                    'ToPort': 443,  
                    'UserIdGroupPairs': [{'GroupId': cloudfront_sg_id}]
                }
            ]
        )

Step 3: Create the VPC endpoint for Private API Gateway

The execute-api VPC Endpoint is configured to route traffic from the internal ALB to the Private API Gateway. Only VPC endpoints can resolve private endpoints and route traffic securely.

  ########### execute-api VPC Endpoint ###########
  ExecuteApiVpcEndpoint:
    Type: AWS::EC2::VPCEndpoint
    Properties:
      ServiceName: !Sub "com.amazonaws.${AWS::Region}.execute-api"
      VpcId: !Ref VPCId
      SubnetIds: !Ref PrivateSubnets
      VpcEndpointType: Interface
      PrivateDnsEnabled: true
      SecurityGroupIds:
        - !Ref VpcEndpointSG 

Step 4: Create the Private API Gateway Resource Policy

The Resource Policy set up on the Private API Gateway only allows traffic from the VPC endpoint placed within the user-defined VPC.

        x-amazon-apigateway-policy:
          Version: "2012-10-17"
          Statement:
          - Effect: "Allow"
            Principal: "*"
            Action: "execute-api:Invoke"
            Resource: "execute-api:/*"
            Condition:
              StringEquals:
                aws:sourceVpce: 
                - !Ref ExecuteApiVpcEndpoint

Testing

Fetch the CloudFront URL from the Outputs section of the deployed stack and test it by using the curl command or your web browser.

curl https://{your custom domain name} 
{"message": "Hello from API GW"}

Conclusion

This post demonstrates how you can establish a secure architecture to access a Private REST API Gateway through a Private ALB, using Amazon CloudFront as the entry point for your application. The solution uses the CloudFront VPC Origins feature, a powerful capability that you can use to directly integrate CloudFront with resources that you host within your Amazon VPC. You can implement this architecture to significantly enhance your application’s security posture as you restrict access to your backend services and minimize the potential attack surface. This approach provides you with a robust and reliable method to protect your applications from unauthorized access while maintaining high availability and performance through the CloudFront global content delivery network.

Building resilient multi-Region Serverless applications on AWS

Post Syndicated from Vamsi Vikash Ankam original https://aws.amazon.com/blogs/compute/building-resilient-multi-region-serverless-applications-on-aws/

Mission-critical applications demand high availability and resilience against potential disruptions. In online gaming, millions of players connect simultaneously, making availability challenges evident. When gaming platforms experience outages, players lose progress, tournaments get disrupted, and brand reputation suffers. Traditional environments often overprovision compute to address these challenges, resulting in complex setups and high infrastructure and operation costs. Modern Amazon Web Services (AWS) serverless infrastructure offers a more efficient approach. This post presents architectural best practices for building resilient serverless applications, demonstrated through a multi-Region serverless authorizer implementation.

Overview

It’s too late if you are recognizing the importance of availability only after experiencing a disaster event. Applications fail for a variety of reasons, such as infrastructure issues, code defects, configuration errors, unexpected traffic spikes, or service disruptions at a regional level. Critical business services such as authentication systems, payment processors, and real-time gaming features necessitate high availability. To minimize impact on user experience and business revenue, establish bounded recovery times for critical services during outages.

AWS serverless architectures inherently provide high availability through multi-Availability Zone (AZ) deployments and built-in scalability. These services minimize infrastructure management while operating on a pay-for-value pricing model at a Regional level. The AWS serverless pay-for-value model enables cost-effective multi-Region deployments, making it ideal for building resilient architectures.

Figure 1. Chart showing various causes of failure, their impact, and how often they happen

Figure 1. Chart showing various causes of failure, their impact, and how often they happen

The preceding chart maps failures—from common operational errors to rare catastrophic events. It guides organizations in prioritizing multi-Region recovery strategies based on the likelihood and the potential impact to the business.

Regional decisions

To determine the appropriate multi-Region approach, carefully evaluate the following factors:

  1. Evaluate if your Recovery Time Objective (RTO) and Recovery Point Objective (RPO) requirements can be met within a single Region, or if a multi-Region architecture is necessary to achieve your recovery objectives.
  2. Do the business benefits of multi-Region redundancy outweigh the operational costs of data replication, synchronization, and increased implementation cost and complexity?
  3. Evaluate if data sovereignty laws, compliance requirements, or geographic restrictions prevent data replication across specific AWS Regions.
  4. Make sure that the chosen Regions in a multi-Region solution have service compatibility, quota limits, and pricing to match your needs.

After evaluating these requirements, if organizations determine the need for multi-Region workloads, then they must choose between two architectural patterns: Active-Passive or Active-Active deployments. Each pattern offers distinct advantages and trade-offs for resilience, costs, and operational complexity.

Multi-Region deployment patterns

The following sections outline the different multi-Region deployment patterns: Active-Passive, and Active-Active.

Active-Passive

In this pattern, one AWS Region serves as the “Active” Region, handling all production traffic, while other Region(s) remain “Passive”, as shown in the following figure. Passive Region(s) replicate data and configurations from the Active Region without serving requests and are prepared to handle requests during service disruptions in the “Active” Region. Depending on application criticality, passive Regions implement varying levels of infrastructure readiness: fully deployed infrastructure (Hot Standby), partially deployed infrastructure (Warm Standby), or minimal core infrastructure (Pilot Light).

Traditional Active-Passive architectures need significant investment in idle infrastructure: load balancers, auto-scaling groups, running compute resources, and monitoring systems. Organizations can use AWS serverless applications, with their pay-for-value pricing, to pay primarily for data replication, not idle compute resources. AWS manages the underlying infrastructure, eliminating most operational overhead.

Service quotas, API limits, and concurrency settings must match between AWS Regions to provide seamless failover. AWS Lambda offers provisioned concurrency to keep functions warm and responsive, which is particularly useful for secondary Regions during failover. It helps reduce cold starts by maintaining warm execution environments, thus the system can handle sudden traffic spikes with fewer cold starts. Note that provisioned concurrency incurs compute costs regardless of usage. Consider implementing auto-scaling for provisioned concurrency based on traffic patterns to optimize costs during idle periods.

This pattern suits organizations seeking a cost-effective disaster recovery (DR) solution, because AWS serverless charges apply only when resources are actively used in the secondary Region. Managed services such as Amazon DynamoDB Global Tables and Amazon Aurora Global Database handle data replication, further streamlining the implementation. The serverless authorizer discussed later in this article demonstrates this pattern in practice.

Figure 2: Active-Passive pattern with dotted lines shows standby Regions, while Active-Active patterns serve concurrent traffic

Figure 2: Active-Passive pattern with dotted lines shows standby Regions, while Active-Active patterns serve concurrent traffic

Active-Active

In this pattern, multiple Regions actively serve traffic concurrently, distributing the load and providing rapid failover capabilities. Active-Active architectures are expensive and designed for highest availability. However, they do not inherently provide DR for all potential failure modes. This approach suits applications needing geolocation-based routing, or highest availability requirements.

Active-Active deployments need rigorous engineering to handle data synchronization and conflict resolution. Each Region must be sized to handle full application load if another Region experiences service impairments. Active users are distributed across AWS Regions, thus a disruption in the service in one Region redirects all of the traffic to the remaining Regions, which necessitates them handling the combined load. To improve application resiliency, implement retry mechanisms, circuit breakers, and fallback strategies. Plan for static stability by pre-provisioning capacity and implementing client-side caching. Services such as Amazon Route 53 with latency-based routing and Amazon DynamoDB Global Tables with strong consistency provide the foundation but need thorough testing under various failure scenarios. This blog will not cover Active-Active deployments.

Multi-Region serverless authorizer

To demonstrate the Active-Passive scenario, we build a sample application that demonstrates how to build a multi-Region serverless authorizer using Amazon API Gateway, Lambda functions, and Amazon Route53. Modern gaming and entertainment platforms host critical services such as player matchmaking, live streaming, and real-time sports analytics. These services depend on robust authorization systems—when authorization fails, players cannot join matches, viewers lose access to streams, and live events becomes inaccessible. This post demonstrates how to build a fault-tolerant, multi-Region serverless authorizer while maintaining lower costs as compared to traditional environments.

Serverless multi-Region architectures typically comprise Routing, Compute, and Data layers. When implementing multi-Region deployments, data replication across AWS Regions is essential, regardless of the compute services used. The compute layer should prioritize idempotency to make sure of safe event processing across AWS Regions. Use Powertools for Lambda for efficient idempotency handling, or implement custom solutions using unique event IDs with DynamoDB as an idempotency store. Although this post focuses on the authorizer service implementation, this pattern can be applied to build multi-Region microservices handling various critical functions, such as game session management, content delivery orchestration, user preference management, and profile services.

Demo overview

To demonstrate the multi-Region serverless authorizer operation, we can examine the workflow:

  1. The frontend application authenticates with the Identity Provider to obtain an authentication token.
  2. The authentication token is sent to a resilient multi-Region DNS endpoint, which is hosted on Route 53 in this demo.
  3. Route 53 routes the request with the token to API Gateway in the primary Region.
  4. Route 53 monitors application health using a mock Lambda function in this demo. In production environments, implement deep health checks to monitor the complete service stack.
  5. Upon successful authorization, the application receives a response. If Route 53 detects primary Region impairment, then it triggers Amazon CloudWatch alarms, which application owners can use to evaluate and approve traffic redirection to the secondary Region.
  6. New traffic routes to the API Gateway in the secondary Region after manual failover approval.
  7. Route 53 health checks continue monitoring the primary Region’s health and restores request traffic when the Region recovers.
Figure 3: Multi-Region serverless authorizer workflow with Route 53 failover between primary and secondary Regions

Figure 3: Multi-Region serverless authorizer workflow with Route 53 failover between primary and secondary Regions

The preceding figure shows the architecture, which demonstrates both failover and fallback capabilities through CloudWatch alarms and a manual approval process. This approach aligns with best practices for critical applications, where automated failover is not recommended despite being technically possible. Teams can use this approach to assess technical readiness, evaluate business impact, and make informed business decisions about timing and potential revenue implications. The demo implements a multi-Region serverless authorizer that serves as a reference architecture. Real-world implementations should carefully evaluate the failover strategies based on business criticality and operational requirements.

Testing multi-Region scenarios

The demo application hosts its frontend on Amazon Elastic Container Service (Amazon ECS). The Route 53 health check configuration in this GitHub defines key failover parameters:

  1. FailureThreshold: Specifies the number of consecutive health check failures before Route 53 marks an endpoint as unhealthy
  2. RequestInterval:
    1. Standard: 30-second interval ($0.50 per health check/month)
    2. Fast: 10-second intervals ($1.00 per health check/month)
```
Route53HealthCheck:
    Type: AWS::Route53::HealthCheck
    Properties:
      HealthCheckConfig:
        FailureThreshold: 2
        FullyQualifiedDomainName: !Ref DomainName
        Port: 443
        RequestInterval: 10
        ResourcePath: /failure
        Type: HTTPS
      HealthCheckTags:
        - Key: Environment
          Value: Production
        - Key: Name
          Value: multi-authorizer-health-check
```

The faster interval enables quicker failure detection. However, it increases health check costs through more logging, request handling, and backend compute resources. Temporary issues such as network glitches, transient errors, or third-party dependency delays may resolve within minutes. Implementing effective retry handling introduces unnecessary complexities and potential data inconsistencies. Choose the appropriate interval based on your business SLAs and cost considerations.

For testing failover scenarios, the architecture uses a mock Lambda function as the health check endpoint. We trigger CloudWatch alarms by simulating a response status code of 500 from this function, which prompts the manual failover decision process, as shown in the following figure.

Figure 4. Console screenshot showing multi-authorizer-health-check with status "Unhealthy"

Figure 4. Console screenshot showing multi-authorizer-health-check with status “Unhealthy”

DNS caching occurs at multiple levels (browser, operating system, ISP, and VPN). To observe failover behavior immediately, clear DNS resolver caches at each level

For more comprehensive resilience testing, consider implementing chaos engineering practices. You can use the chaos-lambda-extension to introduce latency or modify the function responses in a controlled manner. AWS Fault Injection Service (AWS FIS), a fully managed service, enables fault inject experiments to improve application resilience, performance, and observability. Combining these tools helps validate your multi-Region architectures under various controlled failure conditions.

Observability in multi-Region deployments

Implementing a multi-Region architecture is only the first step. Cross-Region observability necessitates monitoring Region A’s resource from Region B and the other way around. CloudWatch enables this through cross-account and cross-Region monitoring, providing consolidated logs and metrics in a single dashboard. Implement deep health checks to verify critical application functionality across AWS Regions.

Although AWS serverless services are distributed, identifying exact failures necessitates combining multiple data points. CloudWatch composite alarms help aggregate these insights, thus facilitating informed decisions. Consider implementing custom monitoring solutions for end-to-end request tracing across AWS Regions. This comprehensive view helps manage the complexity of multi-Region complexity and provides rapid responses to potential issues.

Conclusion

Building resilient multi-Region applications necessitate careful considerations of architecture patterns, costs, and operational complexities. AWS Serverless services, with their pay-for-value model, significantly reduce the challenges to implementing multi-Region architectures. The authorizer pattern demonstrated in this post shows how organizations can achieve high availability without the traditional overhead of idle infrastructure. Teams can follow these architectural patterns and best practices to build robust, cost-effective solutions that maintain service availability during service disruptions.

To learn the concepts of resilience, visit the AWS Developer Center. The complete source code for the demo used in this post is available in our GitHub repository. To expand your serverless knowledge, visit Serverless Land.

Bringing Node.js HTTP servers to Cloudflare Workers

Post Syndicated from Yagiz Nizipli original https://blog.cloudflare.com/bringing-node-js-http-servers-to-cloudflare-workers/

We’re making it easier to run your Node.js applications on Cloudflare Workers by adding support for the node:http client and server APIs. This significant addition brings familiar Node.js HTTP interfaces to the edge, enabling you to deploy existing Express.js, Koa, and other Node.js applications globally with zero cold starts, automatic scaling, and significantly lower latency for your users — all without rewriting your codebase. Whether you’re looking to migrate legacy applications to a modern serverless platform or build new ones using the APIs you already know, you can now leverage Workers’ global network while maintaining your existing development patterns and frameworks.

The Challenge: Node.js-style HTTP in a Serverless Environment

Cloudflare Workers operate in a unique serverless environment where direct tcp connection isn’t available. Instead, all networking operations are fully managed by specialized services outside the Workers runtime itself — systems like our Open Egress Router (OER) and Pingora that handle connection pooling, keeping connections warm, managing egress IPs, and all the complex networking details. This means as a developer, you don’t need to worry about TLS negotiation, connection management, or network optimization — it’s all handled for you automatically.

This fully-managed approach is actually why we can’t support certain Node.js APIs — these networking decisions are handled at the system level for performance and security. While this makes Workers different from traditional Node.js environments, it also makes them better for serverless computing — you get enterprise-grade networking without the complexity.

This fundamental difference required us to rethink how HTTP APIs work at the edge while maintaining compatibility with existing Node.js code patterns.

Our Solution: we’ve implemented the core `node:http` APIs by building on top of the web-standard technologies that Workers already excel at. Here’s how it works:

HTTP Client APIs

The node:http client implementation includes the essential APIs you’re familiar with:

  • http.get() – For simple GET requests

  • http.request() – For full control over HTTP requests

Our implementations of these APIs are built on top of the standard fetch() API that Workers use natively, providing excellent performance while maintaining Node.js compatibility.

import http from 'node:http';

export default {
  async fetch(request) {
    // Use familiar Node.js HTTP client APIs
    const { promise, resolve, reject } = Promise.withResolvers();

    const req = http.get('https://api.example.com/data', (res) => {
      let data = '';
      res.on('data', chunk => data += chunk);
      res.on('end', () => {
        resolve(new Response(data, {
          headers: { 'Content-Type': 'application/json' }
        }));
      });
    });

    req.on('error', reject);

    return promise;
  }
};

What’s Supported

  • Standard HTTP methods (GET, POST, PUT, DELETE, etc.)

  • Request and response headers

  • Request and response bodies

  • Streaming responses

  • Basic authentication

Current Limitations

  • The Agent API is provided but operates as a no-op.

  • Trailers, early hints, and 1xx responses are not supported.

  • TLS-specific options are not supported (Workers handle TLS automatically).

HTTP Server APIs

The server-side implementation is where things get particularly interesting. Since Workers can’t create traditional TCP servers listening on specific ports, we’ve created a bridge system that connects Node.js-style servers to the Workers request handling model.

When you create an HTTP server and call listen(port), instead of opening a TCP socket, the server is registered in an internal table within your Worker. This internal table acts as a bridge between http.createServer executions and the incoming fetch requests using the port number as the identifier.

You then use one of two methods to bridge incoming Worker requests to your Node.js-style server.

Manual Integration with handleAsNodeRequest

This approach gives you the flexibility to integrate Node.js HTTP servers with other Worker features, and allows you to have multiple handlers in your default entrypoint such as fetch, scheduled, queue, etc.

import { handleAsNodeRequest } from 'cloudflare:node';
import { createServer } from 'node:http';

// Create a traditional Node.js HTTP server
const server = createServer((req, res) => {
  res.writeHead(200, { 'Content-Type': 'text/plain' });
  res.end('Hello from Node.js HTTP server!');
});

// Register the server (doesn't actually bind to port 8080)
server.listen(8080);

// Bridge from Workers fetch handler to Node.js server
export default {
  async fetch(request) {
    // You can add custom logic here before forwarding
    if (request.url.includes('/admin')) {
      return new Response('Admin access', { status: 403 });
    }

    // Forward to the Node.js server
    return handleAsNodeRequest(8080, request);
  },
  async queue(batch, env, ctx) {
    for (const msg of batch.messages) {
      msg.retry();
    }
  },
  async scheduled(controller, env, ctx) {
    ctx.waitUntil(doSomeTaskOnSchedule(controller));
  },
};

This approach is perfect when you need to:

  • Integrate with other Workers features like KV, Durable Objects, or R2

  • Handle some routes differently while delegating others to the Node.js server

  • Apply custom middleware or request processing

Automatic Integration with httpServerHandler

For use cases where you want to integrate a Node.js HTTP server without any additional features or complexity, you can use the `httpServerHandler` function. This function automatically handles the integration for you. This solution is ideal for applications that don’t need Workers-specific features.

import { httpServerHandler } from 'cloudflare:node';
import { createServer } from 'node:http';

// Create your Node.js HTTP server
const server = createServer((req, res) => {
  if (req.url === '/') {
    res.writeHead(200, { 'Content-Type': 'text/html' });
    res.end('<h1>Welcome to my Node.js app on Workers!</h1>');
  } else if (req.url === '/api/status') {
    res.writeHead(200, { 'Content-Type': 'application/json' });
    res.end(JSON.stringify({ status: 'ok', timestamp: Date.now() }));
  } else {
    res.writeHead(404, { 'Content-Type': 'text/plain' });
    res.end('Not Found');
  }
});

server.listen(8080);

// Export the server as a Workers handler
export default httpServerHandler({ port: 8080 });
// Or you can simply pass the http.Server instance directly:
// export default httpServerHandler(server);

Express.js, Koa.js and Framework Compatibility

These HTTP APIs open the door to running popular Node.js frameworks like Express.js on Workers. If any of the middlewares for these frameworks don’t work as expected, please open an issue to Cloudflare Workers repository.

import { httpServerHandler } from 'cloudflare:node';
import express from 'express';

const app = express();

app.get('/', (req, res) => {
  res.json({ message: 'Express.js running on Cloudflare Workers!' });
});

app.get('/api/users/:id', (req, res) => {
  res.json({
    id: req.params.id,
    name: 'User ' + req.params.id
  });
});

app.listen(3000);
export default httpServerHandler({ port: 3000 });
// Or you can simply pass the http.Server instance directly:
// export default httpServerHandler(app.listen(3000));

In addition to Express.js, Koa.js is also supported:

import Koa from 'koa';
import { httpServerHandler } from 'cloudflare:node';

const app = new Koa()

app.use(async ctx => {
  ctx.body = 'Hello World';
});

app.listen(8080);

export default httpServerHandler({ port: 8080 });

Getting started with serverless Node.js applications

The node:http and node:https APIs are available in Workers with Node.js compatibility enabled using the nodejs_compat compatibility flag with a compatibility date later than 08-15-2025.

The addition of node:http support brings us closer to our goal of making Cloudflare Workers the best platform for running JavaScript at the edge, whether you’re building new applications or migrating existing ones.

Ready to try it out? Enable Node.js compatibility in your Worker and start exploring the possibilities of familiar HTTP APIs at the edge.

Serverless generative AI architectural patterns – Part 2

Post Syndicated from Michael Hume original https://aws.amazon.com/blogs/compute/part-2-serverless-generative-ai-architectural-patterns/

In Part 1 of this series, we discussed three patterns and general best practices for building real-time, interactive, generative AI applications. However, not all generative AI workflows require immediate responses. This post explores two complementary approaches for non-real-time scenarios: buffered asynchronous processing for time-intensive individual requests, and batch processing for scheduled or event-driven workflows.

Buffered asynchronous processing is useful for use cases demanding time-consuming processing to yield the most precise outcomes. Consequently, these benefit from an interactive delayed request response cycle that can be achieved through a buffered asynchronous integration. Examples include generating video or music from text, conducting medical or scientific analysis and visualization, creating complete virtual worlds for gaming or the metaverse, fashion and lifestyle graphics generation, and more.

The second approach addresses a different challenge: processing extensive datasets on a schedule or when specific events occur. Examples include bulk image enhancement and optimization, weekly or monthly report generation, weekly customer review analysis, and social media content creation. These non-interactive, batch-oriented generative AI workflows necessitate repeatability, scalability, parallelism, and dependency management to manage large data volumes. The non-interactive batch implements this processing pattern.

Pattern 4: Buffered asynchronous request response

This asynchronous pattern uses event-driven architectures to enhance application scalability and reliability. This approach offers several advantages, including improved performance through concurrent processing, enhanced scalability through group processing, and better reliability through decoupled components. This pattern is particularly effective for handling high-volume requests or long-running processes.

The implementation typically involves message queuing services like Amazon Simple Queue Service (Amazon SQS) to buffer requests and manage processing loads. This pattern can be particularly effective when combined with WebSocket APIs for interactive updates, alleviating the need for client-side polling. For complex scenarios involving multiple LLM models, the multimodal fan-out pattern (refer pattern 5 below) using Amazon EventBridge or Amazon Simple Notification Service (Amazon SNS) enables parallel processing across different endpoints. This pattern can be implemented through several architectural approaches.

REST APIs with message queuing

To limit scaling challenges with your LLM endpoint, use an Amazon SQS queue to buffer messages. The frontend sends messages to Amazon API Gateway REST endpoints, which pushes them to the queue. API Gateway returns an acknowledgement and a unique identifier (the message ID) to the frontend. The middleware running on compute services like AWS Lambda, Amazon EC2 or AWS Fargate processes messages in batches, creating entries in Amazon DynamoDB for each record. It then calls LLM endpoints to generate responses, storing the results back in the DynamoDB table with the corresponding message ID. The frontend polls the API Gateway endpoint to check if the response message is generated, querying the DynamoDB table using the message ID. This pattern helps overcome the API Gateway limit of 29 seconds for the request response cycle. For an example implementation, see API Gateway REST API to SQS to Lambda to Bedrock. A similar solution can be implemented using AWS AppSync GraphQL APIs instead of Amazon API Gateway. The following diagram illustrates an example architecture.Fig 1: Buffered asynchronous request response using Amazon API integrations services and Amazon SQS queues

Fig 11: Buffered asynchronous request response using Amazon API integrations services and Amazon SQS queues

WebSocket APIs with message queuing

This is a variation of the previous pattern but uses API Gateway WebSocket APIs instead of REST endpoints. In this pattern, instead of the frontend client having to continuously poll for the response, the middleware sends back the result back to the client after it is generated. This uses WebSocket omni-channel communication to accept and respond to messages, all maintained by API Gateway. For an example implementation, refer to the aws-apigatewayv2websocket-sqs AWS Solutions Construct. The following diagram illustrates this architecture.Fig 2: Buffered asynchronous request response using Amazon API Gateway WebSocket APIs and Amazon SQS queues

Fig 12: Buffered asynchronous request response using Amazon API Gateway WebSocket APIs and Amazon SQS queues

Pattern 5: Multimodal parallel fan-out

For use cases that require interacting with multiple LLM models, data sources, or agents, you can use the messaging fan-out pattern, which distributes messages to multiple destinations in parallel. You can use Amazon EventBridge or Amazon SNS to send specific messages to target LLM endpoints or agents using rules-based message fan-out. This pattern decomposes complex tasks into sub-tasks and executes them in parallel, minimizing overall generation time. For an example implementation, see SNS to SQS fanout pattern. The following diagram illustrates the architecture.Fig 3: Multimodal parallel fan-out using Amazon API integration and messaging services

Fig 13: Multimodal parallel fan-out using Amazon API integration and messaging services

Pattern 6: Non-interactive batch processing

Non-interactive batch processing pipelines are ideal when you need to process large volumes of data efficiently without real-time user interaction, typically running on a scheduled basis to maximize resource usage and throughput. This pattern uses AWS Step Functions, AWS Glue, or other compute services to create a serverless data processing and inferencing pipeline. The data integration, transformation, and inference jobs can be triggered based on a schedule or occurrence of events. This pattern offers higher throughput, optimizes on resource usage, and enhances automation through volume processing. For an example implementation, refer to the aws-sqs-pipes-stepfunctions AWS Solutions Construct. The following diagram illustrates an example architecture.Fig 4: Non-interactive batch processing using Amazon data integration services

Fig 14: Non-interactive batch processing using Amazon data integration services

Conclusion

In this post (series), you learned six architectural patterns on building generative AI applications using AWS serverless services. These patterns implement interactive real-time, asynchronous or batch-oriented workloads without a lot of operational overhead. You can combine these patterns to deliver modern cloud native applications. Given the current trajectory of innovation in this domain, it is anticipated that further blueprints will emerge to augment or evolve these in the future.The successful deployment of production-ready generative AI applications requires careful consideration of architectural patterns and implementation approaches. You must evaluate various factors such as response time, scalability, integration needs, reliability, and user experience when selecting appropriate patterns or a combination of them.

To learn more about Serverless architectures see Serverless Land.

Serverless generative AI architectural patterns – Part 1

Post Syndicated from Michael Hume original https://aws.amazon.com/blogs/compute/serverless-generative-ai-architectural-patterns/

Organizations of all sizes and types are harnessing large language models (LLMs) and foundation models (FMs) to build generative AI applications that deliver new customer and employee experiences. Serverless computing offers the perfect solution, empowering organizations to focus on innovation, flexibility, and cost-efficiency without the complexity of infrastructure management. Organizations transitioning their experimental implementations into production-ready applications can implement proven, scalable, and maintainable software design patterns as the cornerstone of their architecture.

This two-part series explores the different architectural patterns, best practices, code implementations, and design considerations essential for successfully integrating generative AI solutions into both new and existing applications. In this post, we focus on patterns applicable for architecting real-time generative AI applications. Part 2 addresses patterns for building batch-oriented generative AI implementations using serverless services.

Separation of concerns

A fundamental principle in building robust generative AI applications is the separation of concerns, which involves dividing the application stack into three distinct components: frontend, middleware, and backend service layers. This architectural approach (as shown in the following diagram) offers multiple benefits, including reduced complexity, enhanced maintainability, and the ability to scale components independently. By implementing this separation, you can develop cross-platform solutions while maintaining the flexibility to evolve each component according to specific requirements.

1:3 Tier Generative AI Architecture

Fig 1: 3 Tier generative AI Architecture

Although these layers are merely extensions to the traditional software stack, they do perform some specific tasks in generative AI applications.

Frontend layer

The frontend layer serves as the primary interface between end-users and the generative AI application. For organizations integrating generative AI into existing applications, this layer might already be established. The frontend handles critical responsibilities including user authentication, UI/UX presentation, and API communication. AWS provides a robust suite of serverless services to support frontend implementations, including AWS Amplify for full-stack development, Amazon CloudFront paired with Amazon Simple Storage Service (Amazon S3) for content delivery, and container services like Amazon Elastic Container Service (Amazon ECS) and Amazon Elastic Kubernetes Service (Amazon EKS) for application hosting. Specialized services such as Amazon Lex can enhance the user experience through conversational interfaces and intelligent search capabilities for building interactive chatbots.

Middleware layer

This represents the integration layer, comprising of three essential sub-layers that manage different aspects of the application logic and data flow:

  • API layer – This layer exposes backend services through various protocols, including REST, GraphQL, and WebSockets. It handles essential functions such as input validation, traffic management, and CORS support. The API layer also implements authorization and access control mechanisms, manages API versioning, and provides monitoring capabilities. It provides secure and efficient communication between the frontend and backend components while maintaining scalability and reliability. AWS managed services like Amazon API Gateway and AWS AppSync can help create an AI gateway to simplify access and API management.
  • Prompt engineering layer – This layer encapsulates the business logic necessary for interacting with LLMs. It handles dynamic prompt generation, model selection, prompt caching, model routing, guardrails, and security enforcement. This layer implements token and context window optimization, sensitive information filtering, output content moderation, error handling, retry logic, and audit trails. By centralizing these functions, you can maintain consistent prompt strategies, enforce security, and optimize model interactions across applications. You can use Amazon DynamoDB to store prompt templates and configurations, and use Amazon Bedrock Guardrails, Amazon Bedrock prompt caching, and Amazon Bedrock Intelligent Prompt Routing to implement responsible AI safeguards, reuse of prompt prefixes, and dynamic routing, respectively.
  • Orchestration layer – This layer manages complex interactions between various system components. It coordinates external API calls and agent calls, manages vector database queries, stores user sessions and conversation histories, and maintains conversation context across multiple LLM interactions. Frameworks like LangChain and LlamaIndex are commonly used to simplify these operations and provide standardized approaches to common generative AI tasks. AWS Step Functions has direct integrations with over 220 AWS services, including Amazon Bedrock, enabling you to construct intricate generative AI workflows without incurring additional computational resources. Additionally, with Amazon Bedrock Flows, you can create complex, flexible, multi-prompt workflows to evaluate, compare, and version.

Backend services, agents, and private data sources

The backend layer forms the core of generative AI response generation powered by LLMs. It consists of hosting and invoking the LLM model, agents, knowledge bases, or a Model Context Protocol (MCP) server. Amazon Bedrock, Amazon SageMaker JumpStart, and Amazon SageMaker offer a variety of high-performing FMs from leading AI companies or the option to bring your own. You can securely run an MCP server using a containerized architecture, as described in Guidance for Deploying Model Context Protocol Servers on AWS.

Private data sources complement LLMs by providing authoritative proprietary knowledge outside of its training data. For Retrieval Augmented Generation (RAG) implementations, Amazon Kendra, Amazon OpenSearch Serverless, and Amazon Aurora PostgreSQL-Compatible Edition with the pgVector extension provide robust, scalable vector database options. For a deeper dive, please read The role of vector databases in generative AI applications on available AWS service options to store embeddings in a purpose built vector database.

Real-time applications process and deliver responses with minimal latency, enhancing the user experience and facilitating faster decision-making. In the following sections, we explore some architectural patterns that can be used to implement real-time generative AI applications.

Pattern 1: Synchronous request response

In this pattern, responses are generated and immediately delivered, while the client blocks/waits for response. Although this is simple to implement, has a predictable flow, and offers strong consistency, it suffers from blocking operations, high latency, and potential timeouts. When implemented for generative AI applications, this pattern is particularly suited for certain modalities like video or image generations. For fast LLM interactions, it can handle multiple concurrent requests while maintaining consistent performance under varying loads. This model can be implemented through several architectural approaches.

REST APIs

You can use RESTful APIs to communicate with your backend over HTTP requests. You can use REST or HTTP APIs in API Gateway or an Application Load Balancer for path-based routing to the middleware. API Gateway offers additional features like token-based authentication, custom authorizers, resource-based permissions, request/response mapping and transformation, versioning, and rate-limiting. However, with REST/HTTP APIs in API Gateway, the response must be generated within 29 seconds to meet the default integration timeout. You can extend this default limit to 5 minutes for REST APIs with a possible reduction in your AWS Region-level throttle quota for your account. For an example implementation, refer to Interact with Bedrock models from a Lambda function fronted with an API Gateway. The following diagram illustrates this architecture.

Fig 2: Synchronous REST/HTTP APIs using Amazon API Gateway

Fig 2: Synchronous REST/HTTP APIs using Amazon API Gateway

GraphQL HTTP APIs

You can use AWS AppSync as the API layer to take advantage of the benefits of GraphQL APIs. GraphQL APIs offer declarative and efficient data fetching using a typed schema definition, serverless data caching, offline data synchronization, security, and fine-grained access control. It also provides data sources and resolvers for writing business logic. If you don’t need the mutation layer, AWS AppSync can directly invoke an LLM in Amazon Bedrock. AWS AppSync integration timeout is set to 30 seconds by default and can’t be extended. If you need to perform operations that might take longer, consider implementing asynchronous patterns or breaking down the operation into smaller chunks. For an example integration, see Invoke Amazon Bedrock models from AWS AppSync HTTP resolver. The following diagram illustrates the solution architecture.

Fig 3: Synchronous GraphQL HTTP APIs using AWS AppSyncFig 3: Synchronous GraphQL HTTP APIs using AWS AppSync

Conversational chatbot interface

Amazon Lex is a service for building conversational interfaces with voice and text, offering speech recognition and language understanding capabilities. It simplifies multimodal development and enables publication of chatbots to various chat services and mobile devices. It offers native integration with Lambda to streamline chatbot development. When a Lambda function is used for fulfilment, the default response timeout is set to 30 seconds. To bypass, you can use fulfilment updates to provide periodic updates to the user, so the user knows that the chatbot is still working on their request. For an example implementation, see Enhance Amazon Connect and Lex with generative AI capabilities. The following diagram illustrates the solution architecture.

Fig 4: Synchronous conversational APIs using Amazon Lex

Fig 4: Synchronous conversational APIs using Amazon Lex

Model invocation using orchestration

AWS Step Functions enables orchestration and coordination of multiple tasks, with native integrations across AWS services like Amazon API Gateway, AWS Lambda, and Amazon DynamoDB. AWS Step Functions offers built-in features like function orchestration, branching, error handling, parallel processing, and human-in-the-loop capabilities. It also has an optimized integration with Amazon Bedrock, allowing direct invocation of Amazon Bedrock FMs from AWS Step Functions workflows. With this integration, you can accomplish the following:

  • Enrich Step Functions data processing with generative AI capabilities for tasks like text summarization, image generation, or personalization
  • Retrieve and inject up-to-date data (such as product pricing or user profiles) into LLM prompts for improved accuracy
  • Orchestrate LLM and agent calls in a customized processing chain, using the best-suited models at each stage
  • Implement human-in-the-loop interactions to moderate responses and handle hallucinations of the FM

For an example implementation using API Gateway, see Prompt chaining with Amazon API Gateway and AWS Step Functions. For an example implementation using AWS AppSync, see Prompt chaining with AWS AppSync, AWS Step Functions and Amazon Bedrock. The following diagram illustrates an example architecture.

Fig 5: Synchronous model invocations using AWS Step FunctionsFig 5: Synchronous model invocations using AWS Step Functions

Pattern 2: Asynchronous request response

This pattern provides a full-duplex, bidirectional communication channel between the client and server without clients having to wait for updates. The biggest advantages is its non-blocking nature that can handle long-running operations. However, they are more complex to implement because they require channel, message, and state management. This model can be implemented through two architectural approaches.

WebSocket APIs

The WebSocket protocol enables real-time, synchronous communication between the frontend and middleware, allowing for bidirectional, full-duplex messaging over a persistent TCP connection. This bidirectional behavior enhances client/service interactions, enabling services to push data to clients without requiring explicit requests. Using API Gateway, you can create a WebSocket APIs as a stateful frontend for an AWS service (such as Lambda or DynamoDB) or for an HTTP endpoint. The WebSocket API invokes your backend based on the content of the messages it receives from client apps. After the message is generated, the backend can send callback messages to connected clients. Each request-response cycle must complete within 29 seconds, as defined by the API Gateway integration timeout for WebSockets. The connection duration for API Gateway WebSocket APIs can be up to 2 hours with an idle connection timeout of 10 minutes—these can’t be extended. For an example implementation, refer to AI Chat with Amazon API Gateway (WebSockets), AWS Lambda and Amazon Bedrock. The following diagram illustrates an example architecture.

Fig 6: Asynchronous WebSocket APIs using Amazon API GatewayFig 6: Asynchronous WebSocket APIs using Amazon API Gateway

GraphQL WebSocket APIs

AWS AppSync can establish and maintain secure WebSocket connections for GraphQL subscription operations, enabling middleware applications to distribute data in real time from data sources to subscribers. It also supports a simple publish-subscribe model, where client frontends can listen to specific channels or topics, with AWS AppSync managing multiple temporary pub/sub channels and WebSocket connections to deliver and filter data based on the channel name. For an example implementation, refer to AI Chat with AWS AppSync (WebSockets), AWS Lambda, and Amazon Bedrock. The following diagram illustrates an example architecture.Fig 7: Asynchronous GraphQL WebSocket APIs using AWS

Fig 7: Asynchronous GraphQL WebSocket APIs using AWS

Pattern 3: Asynchronous streaming response

This streaming pattern enables real-time response flow to clients in chunks, enhancing the user experience and minimizing first response latency. This pattern uses built-in streaming capabilities in services like Amazon Bedrock (InvokeModelWithResponseStream or ConverseStream APIs) and SageMaker real-time inference, enabling applications to display results incrementally rather than waiting for complete responses. This pattern is particularly effective for applications implementing text modality such as chat interfaces and word-based content generation tools.

Implementation is achieved through the API Gateway WebSocket API or AWS AppSync WebSocket APIs or GraphQL subscriptions, with careful consideration given to timeout management and connection handling.

The following diagram illustrates the architecture of asynchronous streaming using API Gateway WebSocket APIs.Fig 8: Asynchronous streaming response using Amazon API Gateway WebSockets APIs

Fig 8: Asynchronous streaming response using Amazon API Gateway WebSockets APIs

The following diagram illustrates the architecture of asynchronous streaming using AWS AppSync WebSocket APIs.Fig 9: Asynchronous streaming response using AWS AppSync WebSocket APIs

Fig 9: Asynchronous streaming response using AWS AppSync WebSocket APIs

If you don’t need an API layer, Lambda response streaming lets a Lambda function progressively stream response payloads back to clients. For more details, see Using Amazon Bedrock with AWS Lambda. The following diagram illustrates this architecture.Fig 10: Asynchronous response using AWS Lambda response streaming

Fig 10: Asynchronous response using AWS Lambda response streaming

Conclusion

This post introduced three design patterns applicable for real-time generative AI applications: synchronous request response, asynchronous request response, and asynchronous streaming response. We also highlighted how to implement these patterns using AWS serverless services. When selecting an appropriate pattern for your implementation, it is crucial to consider the anticipated end-user experience, the existing technical stack, AWS service quotas, and the latency of your LLM responses. In Part 2, we discuss patterns for building batch-oriented generative AI implementations using AWS serverless services.

How AppZen enhances operational efficiency, scalability, and security with Amazon OpenSearch Serverless

Post Syndicated from Prashanth Dudipala, Madhuri Andhale original https://aws.amazon.com/blogs/big-data/how-appzen-enhances-operational-efficiency-scalability-and-security-with-amazon-opensearch-serverless/

AppZen is a leading provider of AI-driven finance automation solutions. The company’s core offering centers around an innovative AI platform designed for modern finance teams, featuring expense management, fraud detection, and autonomous accounts payable solutions. AppZen’s technology stack uses computer vision, deep learning, and natural language processing (NLP) to automate financial processes and ensure compliance. With this comprehensive solution approach, AppZen has a well-established enterprise customer base that includes one-third of the Fortune 500 companies.

AppZen hosts all its workloads and application infrastructure on Amazon Web Services (AWS), continuously modernizing its technology stack to effectively operationalize and host its applications. Centralized logging, a critical component of this infrastructure, is essential for monitoring and managing operations across AppZen’s diverse workloads. As the company experienced rapid growth, the legacy logging solution struggled to keep pace with expanding needs. Consequently, modernizing this system became one of AppZen’s top priorities, prompting a comprehensive overhaul to enhance operational efficiency and scalability.

In this blog we show, how AppZen modernizes its central log analytics solution from Elasticsearch to Amazon OpenSearch Serverless providing an optimized architecture to meet above mentioned requirements.

Challenges with the legacy logging solution

With a growing number of business applications and workloads, AppZen had an increasing need for comprehensive operational analytics using log data across its multi-account organization in AWS Organizations. AppZen’s legacy logging solution created several key challenges. It lacked the flexibility and scalability to efficiently index and make the logs available for real-time analysis, which was crucial for tracking anomalies, optimizing workloads, and ensuring efficient operations.

The legacy logging solution consisted of a 70-node Elasticsearch cluster (with 30 hot nodes and 40 warm nodes), it struggled to keep up with the growing volume of log data as AppZen’s customer base expanded and new mission-critical workloads were added. This led to performance issues and increased operational complexity. Maintaining and managing the self-hosted Elasticsearch cluster required frequent software updates and infrastructure patching, resulting in system downtime, data loss, and added operational overhead for the AppZen CloudOps team.

Migrating the data to a patched node cluster took 7 days, far exceeding industry standard and AppZen’s operational requirements. This extended downtime introduced data integrity risk and directly impacted the operational availability of the centralized logging system crucial for teams to troubleshoot across critical workloads. The system also suffered frequent data loss that impacted real-time metrics monitoring, dashboarding, and alerting because its application log-collecting agent Fluent Bit lacked essential features such as backoff and retry.

AppZen has an NGINX proxy instance controlling authorized user access to data hosted on Elasticsearch. Upgrades and patching of the instance introduced frequent system downtimes. All user requests are routed through this proxy layer, where the user’s permission boundary is evaluated. This had an added operations overhead for administrators to manage users and group mapping at the proxy layer.

Solution overview

AppZen re-platformed its central log analytics solution with Amazon OpenSearch Serverless and Amazon OpenSearch Ingestion. Amazon OpenSearch Serverless lets you run OpenSearch in the AWS Cloud, so you can run large workloads without configuring, managing, and scaling OpenSearch clusters. You can ingest, analyze, and visualize your time-series data without infrastructure provisioning. OpenSearch Ingestion is a fully managed data collector that simplifies data processing with built-in capabilities to filter, transform, and enrich your logs before analysis.

This new serverless architecture, shown in the following architecture diagram, is cost-optimized, secure, high-performing, and designed to scale efficiently for future business needs. It serves the following use cases:

  • Centrally monitor business operations and data analysis for deep insights
  • Application monitoring and infrastructure troubleshooting

Together, OpenSearch Ingestion and OpenSearch Serverless provide a serverless infrastructure capable of running large workloads without configuring, managing, and scaling the cluster. It provides data resilience with persistent buffers that can support the current 2 TB per day pipeline data ingestion requirement. IAM Identity Center support for OpenSearch Serverless helped manage users and their access centrally eliminating a need for NGINX proxy layer.

The architecture diagram also shows how separate ingestion pipelines were deployed. This configuration option improves deployment flexibility based on the workload’s throughput and latency requirements. In this architecture, Flow-1 is a push-based data source (such as HTTP and OTel logs) where the workload’s Fluent Bit DaemonSet is configured to ingest log messages into the OpenSearch Ingestion pipeline. These messages are retained in the pipeline’s persistent buffer to provide data durability. After processing the message, it’s inserted into OpenSearch Serverless.

And Flow-2 is a pull-based data source such as Amazon Simple Storage Service (Amazon S3) for OpenSearch Ingestion where the workload’s Fluent Bit DaemonSets are configured to sync data to an S3 bucket. Using S3 Event Notifications, the new log records creation notifications are sent to Amazon Simple Queue Service (Amazon SQS). OpenSearch Ingestion consumes this notification and processes the record to insert into OpenSearch Serverless, delegating the data durability to the data source. For both Flow-1 and Flow-2, the OpenSearch Ingestion pipelines are configured with a dead-letter queue to record failed ingestion messages to the S3 source, making them accessible for further analysis.

AWS logging architecture with ingestion flows to OpenSearch Serverless

For service log analytics, AppZen adopted a pull-based approach as shown in the following figure, where all service logs published to Amazon CloudWatch are migrated an S3 bucket for further processing. An AWS Lambda processor is triggered when every new message is ingested to the S3 bucket, and the processed message is then uploaded to the S3 bucket for OpenSearch ingestion. The following diagram shows the OpenSearch Serverless architecture for the service log analytics pipeline.

A log ingestion architecture for service log analytics

Workloads and infrastructure spread across multiple AWS accounts can securely send logs to the central log analytics platform over a private network using virtual private cloud (VPC) peering and AWS PrivateLink endpoints, as shown in the following figure. Both OpenSearch Ingestion and OpenSearch Serverless are provisioned in the same account and Region, with cross-account ingestion enabled for workloads in other member accounts of the AWS Organizations account.

Cross-account AWS logging with secure centralized collection

Migration approach

The migration to OpenSearch Serverless and OpenSearch Ingestion involved performance evaluation and fine-tuning the configuration of the logging stack, followed by migration of production traffic to new platform. The first step was to configure and benchmark the infrastructure for cost-optimized performance.

Parallel ingestion to benchmark OCU capacity requirements

OpenSearch Ingestion scales elastically to meet throughput requirements during workload spikes. Enabling persistent buffering on ingestion pipelines with push-based data sources provided data durability and reliability. Data ingestion pipelines are ingesting at a rate of 2 TB per day. Due to AppZen’s 90-day data retention requirement around its ingested data, at any time, there is approximately 200 TB of indexed historical data stored in the OpenSearch Serverless cluster. To evaluate performance and costs before deploying to production, data sources were configured to ingest data in parallel into the new OpenSearch Serverless environment along with an existing setup already running in production with Elasticsearch.

To achieve parallel ingestion, AppZen installed another Fluent Bit DaemonSet configured to ingest into the new pipeline. This was for two reasons: 1) To avoid interruption due to changes to existing ingestion flow and 2) New workflows are much more straightforward when the data preprocessing step is offloaded to OpenSearch Ingestion, eliminating the need for custom lua script use in Fluent Bit.

Pipeline configuration

The production pipeline configuration was implemented with different strategies based on data source types. Push-based data sources were configured with persistent buffer enabled for data durability and a minimum of three OpenSearch Compute Units (OCUs) to provide high availability across three Availability Zones. In contrast, pull-based data sources, which used Amazon S3 as their source, didn’t require persistent buffering due to the inherent durability features of Amazon S3. Both pipeline types were initially configured with a minimum of three OCUs and a maximum of 50 OCUs to establish baseline performance metrics. This setup meant the team could monitor and analyze actual workload patterns, and therefore fine-tune worker configurations for optimal OCU usage. Through continuous monitoring and adjustment, the pipeline configurations were changed and optimized to efficiently handle both daily average loads and peak traffic periods, providing cost-effective and reliable data processing operations.

For AppZen’s throughput requirement, in the pull-based approach, they identified six Amazon S3 workers in the OpenSearch Ingestion pipelines optimally processing 1 OCU at 80% efficiency. Following the best practices recommendation, at this system.cpu.usage.value metrics threshold, the pipeline was configured to auto scale. With each worker capable of processing 10 messages, AppZen identified cost-optimized configuration of 50 OCUs as maximum OCU configuration for its pipelines that is capable of processing up to 3,000 messages in parallel. This pipeline configuration shown below supports its peak throughput requirements

# This is an OpenSearch Ingestion - pipeline configuration for processing Kubernetes logs and sending them to OpenSearch Serverless
# Data Flow: S3 -> SQS -> OpenSearch Ingestion -> OpenSearch + S3 Archive
# index_name here is kubernetes.namespace_name or k8 service name
# If k8 Index name is dev: Service1-dev
# If k8 Index name is non-dev: Service1-allenv
version: "2"
entry-pipeline:
  # Source (S3 + SQS)
  # Reads logs from S3 bucket via SQS notifications
  # 6 workers process JSON files. Deletes S3 objects after processing
  source:
    s3:
      workers: 6
      notification_type: "sqs"
      codec:
        ndjson:
      compression: "none"
      aws:
        region: "us-east-1"
        sts_role_arn: "<roleArn>"
      acknowledgments: true
      delete_s3_objects_on_read: true
      sqs:
        queue_url: "https://sqs.us-east-1.amazonaws.com/********1234/us-s3-k8-log"
        visibility_duplication_protection: true
  # Processing Pipeline
  # Timestamp: Adds @timestamp from ingestion time
  # Index naming: Sets index_name from Kubernetes namespace
  processor:
    - date:
        from_time_received: true
        destination: "@timestamp"
    - add_entries:
        entries:
        - key: "index_name"
          value_expression: "/kubernetes_namespace/name"
          add_when: "/index_name == null"
    - delete_entries:
        with_keys: [ "tmp" ]
    
    # JSON parsing: Parses nested JSON in log and message fields
    # Failed JSON parsing skipped silently
    - parse_json:
        source: /log
        handle_failed_events: 'skip_silently'
    - parse_json:
        source: /message
        handle_failed_events: 'skip_silently'
    
    # Environment detection: Uses grok patterns to extract environment from namespace names
    - grok:
        grok_when: 'contains(/index_name, "prod-") or contains(/index_name, "prod-k1-") or contains(/index_name, " prod-k2-")'
        match:
          index_name:
            - '%{WORD:prefix}-%{GREEDYDATA:suffix}-%{INT:ignore}'
            - '%{WORD:prefix}-%{GREEDYDATA:suffix}'
    - add_entries:
        entries:
        - key: "/suffix"
          value_expression: "/index_name"
          add_when: "/suffix == null"
        - key: "/labels/environment"
          value_expression: "/prefix"
          add_when: "/prefix != null"
          overwrite_if_key_exists: true
        - key: "/labels/environment"
          value_expression: "/labels_environment"
          add_when: "/labels_environment != null"
          overwrite_if_key_exists: true
  # Routing Logic 
  # k8: Normal Kubernetes logs
  # k8-debug: DEBUG level logs (separate retention)
  # unknown: Logs without proper metadata
  routes:
    - k8: '/kubernetes_namespace/name != null or /data_source == "kubernetes"'
    - k8-debug: '/data_source == "kubernetes" and /levelname == "DEBUG"'
    - unknown: '/kubernetes_namespace/name == null and /suffix == null and /log_group == null'
  # Sinks (3 destinations)
  # S3 Archive: All logs stored in S3 with date partitioning
  # OpenSearch (Normal): ${suffix}-v4-k8 index for regular logs
  # OpenSearch (Debug): ${suffix}-v4-k8-debug index for debug logs
  sink:
    - s3:
        aws:
          region: "us-east-1"
          sts_role_arn: "<roleArn>"
        bucket: <logS3Bucket>
        object_key:
          path_prefix: 'us/${getMetadata("s3-prefix")}/%{yyyy}/%{MM}/%{dd}/'
        codec:
          json:
        compression: "none"
        threshold:
          maximum_size: 20mb
          event_collect_timeout: PT10M
    - opensearch:
        hosts: ["https://<AossDomainUrl>"]
        index: "${/suffix}-v4-k8"
        index_type: custom
        # Max 15 retries for OpenSearch operations
        max_retries: 15
        aws:
          # IAM role that the pipeline assumes to access the domain sink
          sts_role_arn: "<roleArn>"
          region: "us-east-1"
          serverless: true
          serverless_options:
            network_policy_name: "prod-logging-network"
        # Error Handling:
        # Dead Letter Queue (DLQ) to S3 for failed OpenSearch writes
        dlq:
          s3:
            bucket: "<dlqS3Bucket>"
            key_path_prefix: "/k8/"
            region: "us-east-1"
            sts_role_arn: "<roleArn>"
        routes:
          - k8
    - opensearch:
        hosts: ["https://<AossDomainUrl>"]
        index: "${/suffix}-v4-k8-debug"
        index_type: custom
        max_retries: 15
        aws:
          # IAM role that the pipeline assumes to access the domain sink
          sts_role_arn: "<roleArn>"
          region: "us-east-1"
          serverless: true
          serverless_options:
            network_policy_name: "prod-logging-network"
        dlq:
          s3:
            bucket: "<dlqS3Bucket>"
            key_path_prefix: "/k8-debug/"
            region: "us-east-1"
            sts_role_arn: "<roleArn>"
        routes:
          - k8-debug
    - opensearch:
        hosts: ["https://<AossDomainUrl>"]
        index: "unknown"
        index_type: custom
        max_retries: 15
        aws:
          # IAM role that the pipeline assumes to access the domain sink
          sts_role_arn: "<roleArn>"
          region: "us-east-1"
          serverless: true
          serverless_options:
            network_policy_name: "prod-logging-network"
        dlq:
          s3:
            bucket: "<dlqS3Bucket>"
            key_path_prefix: "/unknown/"
            region: "us-east-1"
            sts_role_arn: "<roleArn>"
        routes:
          - unknown

Indexing strategy

When working with search engine, understanding index and shard management is crucial. Indexes and their corresponding shards consume memory and CPU resources to maintain metadata. A key challenge emerges when having numerous small shards in a system because it leads to higher resource consumption and operational overhead. In the traditional approach, you typically create indices at the microservice level for each environment (prod, qa, and dev). For example, indices would be named like prod-k1-service or prod-k2-service, where k1 and k2 represent different microservices. With hundreds of services and daily index rotation, this approach results in thousands of indices, making management complex and resource intensive. When implementing OpenSearch Serverless, you should adopt a consolidated indexing strategy that moves away from microservice-level index creation. Rather than creating individual indices like prod-k1-service and prod-k2-service for each microservice and environment, you should consolidate the data into broader environment-based indices such as prod-service, which contains all service data for the production environment. This consolidation is essential because OpenSearch Serverless scales based on resources and has specific limitations on the number of shards per OCU. This means that having a higher number of small shards will lead to higher OCU consumption.

However, although this consolidated approach can significantly reduce operational costs and simplify management through built-in data lifecycle policies, it presents a notable challenge for multi-tenant scenarios. Organizations with strict security requirements, where different teams need access to specific indices only, might find this consolidated approach challenging to implement. For such cases, a more granular indices approach might be necessary to maintain proper access control, even though it can result in higher resource consumption.

By carefully evaluating your security requirements and access control needs, you can choose between a consolidated approach for optimized resource utilization or a more granular approach that better supports fine-grained access control. Both approaches are supported in OpenSearch Serverless, so you can balance resource optimization with security requirements based on your specific use case.

Cost optimization

OpenSearch Ingestion allocates some OCUs from configured pipeline capacity for persistent buffering, which provides data durability. While monitoring, AppZen observed higher OCU usage for this persistent buffer when processing high-throughput workloads. To optimize this capacity configuration, AppZen decided to classify its workloads into push-based and pull-based categories depending on their throughput and latency requirements. Achieving this created new parallel pipelines to operate these flows in parallel, as shown in the architecture diagram earlier in the post. Fluent Bit agent collector configurations were accordingly modified based on the workload classification.

Depending on the cost and performance requirements for the workload, AppZen adopted the appropriate ingestion flow. For low latency and low-throughput workload requirements, AppZen chose the push-based approach. For high-throughput workload requirements, AppZen adopted the pull-based approach, which helped lower the persistent buffer OCU usage by relying on durability to the data source. In the pull-based approach, AppZen further optimized on the storage cost by configuring the pipeline to automatically delete the processed data from the S3 bucket after successful ingestion

Monitoring and dashboard

One of the key design principles for operational excellence in the cloud is to implement observability for actionable insights. This helps gain a comprehensive understanding of the workloads to help improve performance, reliability, and the cost involved. Both OpenSearch Serverless and OpenSearch Ingestion publish all metrics and logs data to Amazon CloudWatch. After identifying key operational OpenSearch Serverless metrics and OpenSearch Service pipeline metrics, AppZen set up CloudWatch alarms to send a notification when certain defined thresholds are met. The following screenshot shows the number of OCUs used to index and search collection data.

OpenSearch Serverless capacity management dashboard showing OCU usage graphs

The following screenshot shows the number of Ingestion OCUs in use by the pipeline.

The following screenshot shows the percentage of available CPU usage for OCU.

The following screenshot shows the percent usage of buffer based on the number of records in the buffer.

Conclusion

AppZen successfully modernized their logging infrastructure by migrating to a serverless architecture using Amazon OpenSearch Serverless and OpenSearch Ingestion. By adopting this new serverless solution, AppZen eliminated an operations overhead that involved 7 days of data migration effort during each quarterly upgrade and patching cycle of Kubernetes cluster hosting Elasticsearch nodes. Also, with the serverless approach, AppZen was able to avoid index mapping conflicts by using index templates and a new indexing strategy. This helped the team save an average 5.2 hours per week of operational effort and instead use the time to focus on other priority business challenges. AppZen achieved a better security posture through centralized access controls with OpenSearch Serverless, eliminating the overhead of managing a duplicate set of user permissions at the proxy layer. The new solution helped AppZen handle growing data volume and build real-time operational analytics while optimizing cost, improving scalability and resiliency. AppZen optimized costs and performance by classifying workloads into push-based and pull-based flows, so they could choose the appropriate ingestion approach based on latency and throughput requirements.

With this modernized logging solution, AppZen is well positioned to efficiently monitor their business operations, perform in-depth data analysis, and effectively monitor and troubleshooting the application as they continue to grow. Looking ahead, AppZen plans to use OpenSearch Serverless as a vector database, incorporating Amazon S3 Vectors, generative AI, and foundation models (FMs) to enhance operational tasks using natural language processing.

To implement a similar logging solution for your organization, begin by exploring AWS documentation on migrating to Amazon OpenSearch Serverless and setting up OpenSearch Serverless. For guidance on creating ingestion pipelines, refer to the AWS guide on OpenSearch Ingestion to begin modernizing your logging infrastructure.


About the authors

Prashanth Dudipala is a DevOps Architect at AppZen, where he helps build scalable, secure, and automated cloud platforms on AWS. He’s passionate about simplifying complex systems, enabling teams to move faster, and sharing practical insights with the cloud community.
Madhuri Andhale is a DevOps Engineer at AppZen, focused on building and optimizing cloud-native infrastructure. She is passionate about managing efficient CI/CD pipelines, streamlining infrastructure and deployments, modernizing systems, and enabling development teams to deliver faster and more reliably. Outside of work, Madhuri enjoys exploring emerging technologies, traveling to new places, experimenting with new recipes, and finding creative ways to solve everyday challenges.
Manoj Gupta is a Senior Solutions Architect at AWS, based in San Francisco. With over 4 years of experience at AWS, he works closely with customers like AppZen to build optimized cloud architectures. His primary focus areas are Data, AI/ML, and Security, helping organizations modernize their technology stacks. Outside of work, he enjoys outdoor activities and traveling with family.
Prashant Agrawal is a Sr. Search Specialist Solutions Architect with Amazon OpenSearch Service. He works closely with customers to help them migrate their workloads to the cloud and helps existing customers fine-tune their clusters to achieve better performance and save on cost. Before joining AWS, he helped various customers use OpenSearch and Elasticsearch for their search and log analytics use cases. When not working, you can find him traveling and exploring new places. In short, he likes doing Eat → Travel → Repeat.
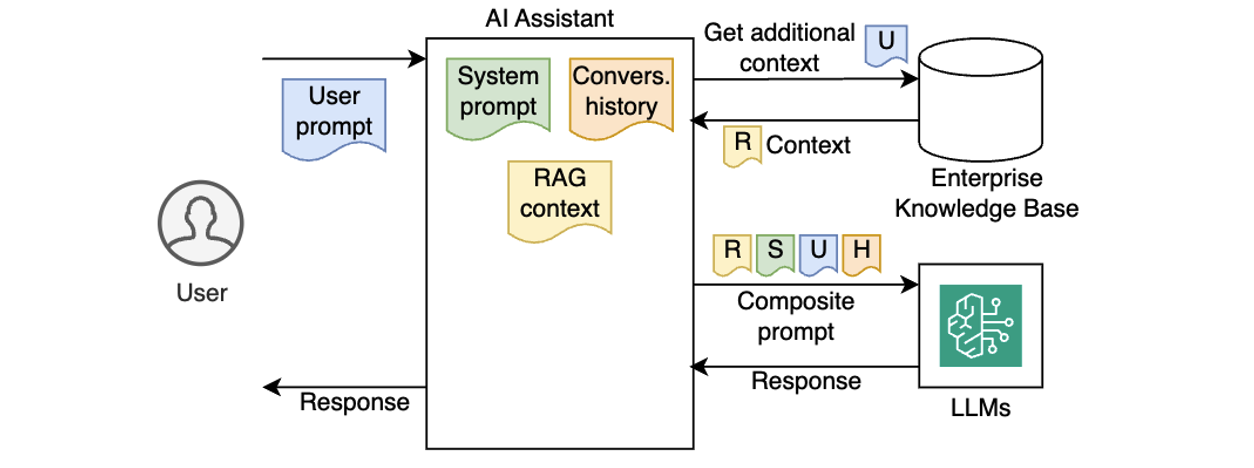
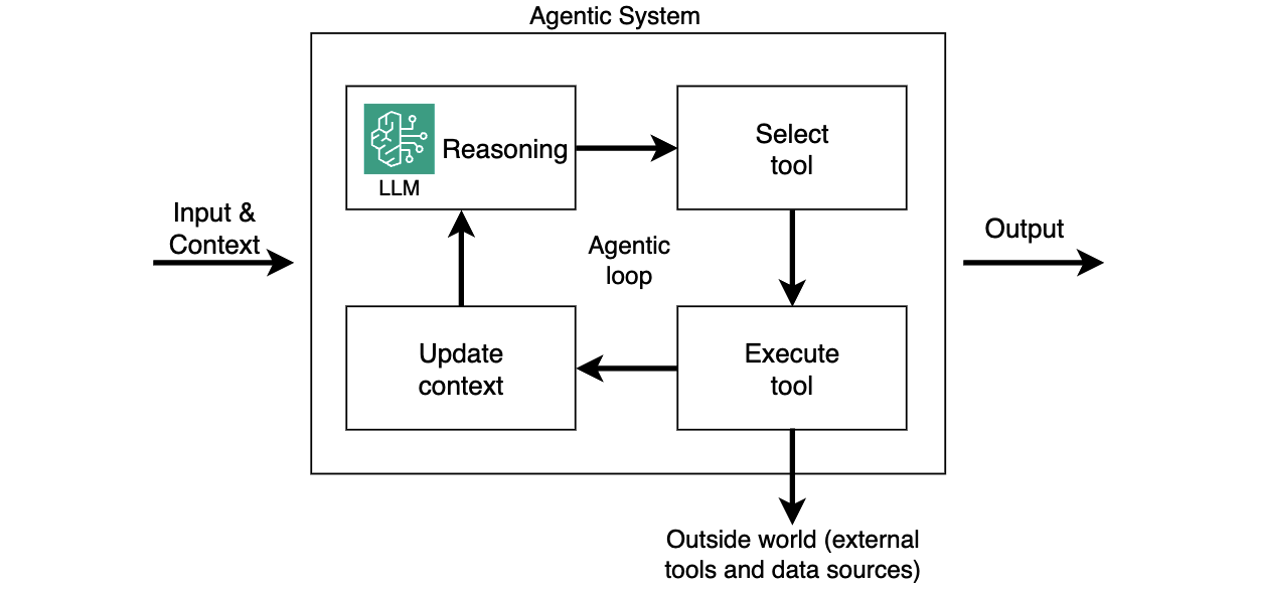
Amazon Redshift Serverless at 4 RPUs: High-value analytics at low cost

Post Syndicated from Ricardo Serafim original https://aws.amazon.com/blogs/big-data/amazon-redshift-serverless-at-4-rpus-high-value-analytics-at-low-cost/

Organizations across industries struggle with the economics of data analytics. High entry costs, complex capacity planning, and unpredictable workload demands create barriers that prevent teams from accessing the insights they need. Small businesses abandon analytics initiatives due to prohibitive minimums, and enterprises overprovision resources for development environments, leading to inefficient spending.

Amazon Redshift Serverless now addresses these challenges with 4 RPU configurations, helping you get started with a lower base capacity that runs scalable analytics workloads beginning at $1.50 per hour. This new option transforms the economics of data analytics with the flexibility to scale up automatically based on workload demands. You only pay for the compute capacity you consume, calculated on a per-second basis.

With 64 GB of memory and support for up to 32 TB of managed storage, this lower entry point offering addresses several common customer needs, including development and test environments that maintain separate workloads at lower cost and production workloads with variable demand that need cost-effective scaling. The configuration is particularly useful for test and development environments, departmental data warehouses, periodic reporting workloads, gaming analytics, and data mesh architectures with unpredictable usage patterns. Organizations just starting with cloud analytics can use this low-cost option while getting access to enterprise features like automatic scaling, built-in security, and seamless data lake integration.In this post, we examine how this new sizing option makes Redshift Serverless accessible to smaller organizations while providing enterprises with cost-effective environments for development, testing, and variable workloads.

New 4 RPU minimum base capacity in Redshift Serverless

Redshift Serverless measures compute capacity using Redshift Processing Units (RPUs), where each RPU provides 16 GB of memory. With this new minimum base capacity, the 4 RPU configuration delivers a total of 64 GB of memory. It supports up to 32 TB of managed storage, with a maximum of 100 columns per table. The 4 RPU configuration is cost-efficient, and it’s designed for lighter workloads. When your workload requires additional resources, Redshift Serverless automatically scales up the compute capacity. After you have scaled beyond 4 RPUs, your data warehouse will continue using the higher RPU level to maintain consistent performance. This behavior provides workload stability while preserving the benefits of automatic scaling.

For workloads requiring more resources, such as tables with a large number of columns or higher concurrency requirements, you can choose higher base capacities ranging from 8 RPUs up to 1024 RPUs. This flexibility helps you start small and adjust your resources as your analytics requirements evolve.

Benefits of Redshift Serverless with 4 RPUs

This new feature offers the following benefits:

  • Cost-effective entry point – The new 4 RPU configuration is a low-cost option for cloud data warehousing, making enterprise-grade analytics accessible to organizations of various sizes, such as startups exploring their first data warehouse or established enterprises optimizing their analytics spending. For example, in the US East (N. Virginia) Region, the compute cost is $0.375 per RPU-hour. For a 4 RPU base capacity, this translates to $1.50 per hour of active workload time. Because you’re only charged when workloads are running, small-scale users can keep costs predictable and low. This configuration helps teams begin their analytics journey with minimal upfront commitment. Development teams can maintain dedicated environments for testing and experimentation without significant cost overhead.
  • Support for smaller datasets – With support for up to 32 TB of Redshift Managed Storage, the 4 RPU configuration is well-suited for smaller data warehouses. It can handle datasets ranging from a few gigabytes to tens of terabytes, making it ideal for startups, small businesses, or departments with limited data volumes.
  • Seamless integration with the AWS ecosystem – The 4 RPU configuration integrates seamlessly with other AWS services, such as Amazon Simple Storage Service (Amazon S3) for data lakes, AWS Glue for ETL (extract, transform, and load), and Amazon QuickSight for visualization. This makes it straightforward to build end-to-end analytics pipelines, even for smaller-scale projects. Additionally, Redshift data lake queries on external Amazon S3 data are included in the RPU billing, simplifying cost management.
  • Use case flexibility – The 4 RPU configuration proves valuable across numerous analytics scenarios. Development and testing environments benefit from cost-effective isolation, and departmental data warehouses can start small and scale as needed. Organizations running periodic reporting workloads or proof-of-concept projects can optimize costs by paying only for actual usage. Even small to medium-sized production workloads can use this configuration effectively.

Regardless of the use case, you can benefit from the full feature set of Redshift Serverless, including built-in security, data lake integration, and automated maintenance.

Use cases for Redshift Serverless with 4 RPU workgroups

The 4 RPU configuration is tailored for scenarios where lightweight compute resources suffice. The following are some practical use cases:

  • Small business analytics – Small businesses with limited data (less than 32 GB) can analyze sales, customer behavior, or operational metrics with cost-effective data warehouses. Running 10–20 daily ETL queries and occasional one-time queries remains cost-effective at this capacity.
  • Development and testing environments – The configuration is well-suited for development and test environments where full production resources aren’t needed. Data engineers can experiment with Redshift Serverless, prototype queries, or build proof-of-concept solutions without committing to higher RPU capacities. The 4 RPU configuration lowers the cost of continuous integration and delivery (CI/CD) testing of data pipelines. Teams can run automated integration tests and schema validations in isolated environments that mirror production systems while optimizing costs through per-second billing.
  • Analytics for startups – Startups can build robust product analytics capabilities without significant upfront investment. Teams can track customer behavior, feature adoption, and KPIs using familiar SQL queries, then connect business intelligence (BI) tools like Quicksight or Tableau for lightweight dashboarding.
  • Training and experimentation – Organizations can create dedicated sandbox environments for data analysts’ onboarding and experimentation with minimal budget impact. These environments are perfect for exploring analytics powered by large language models (LLMs), semantic layer development, or generative AI applications.
  • Data quality workflows – The feature efficiently supports scheduled jobs for data quality validation, checking data freshness, integrity, and conformance without dedicating high-capacity environments to routine QA tasks.
  • Enterprise team enablement – Large organizations can implement decentralized data warehousing strategies. Each department can operate its data warehouse aligned with specific needs and budgets, enabling department-level chargeback models.
  • Environment isolation – Organizations can create dedicated workgroups per environment (development, test, QA, UAT), providing complete isolation without sharing compute resources or risking cross-environment interference.
  • Data mesh architecture – Domain teams can operate independently while maintaining cost-efficiency. Each domain runs its workgroup for lightweight transformations, domain-specific marts, and KPI calculations. It offers a flexible sizing option in a data mesh architecture.
  • Event-driven analytics – Well-suited for short-lived or event-triggered analytics tasks. Organizations can programmatically create workgroups through APIs for A/B test analysis, campaign performance summaries, or machine learning (ML) pipeline validation.
  • Low-volume one-time reporting – Organizations with infrequent or lightweight reporting needs, such as monthly financial summaries or dashboard refreshes, can use 4 RPUs to minimize costs while maintaining performance.

Cost considerations and best practices

Although the 4 RPU configuration is cost-effective, there are a few considerations to keep in mind to optimize expenses:

  • Billing – Redshift Serverless bills on a per-second basis with a 60-second minimum per query. For very short queries (such as subsecond), this can inflate costs. To mitigate this, batch queries where possible to maximize resource utilization within the 60-second window. For more information, see Amazon Redshift pricing.
  • Set usage limits – Use the Redshift Serverless console to set maximum RPU-hour limits (daily, weekly, or monthly) to prevent unexpected costs. You can configure alerts or automatically turn off queries when limits are reached. To learn more, see Setting usage limits, including setting RPU limits.
  • Monitor with system views – Query the SYS_SERVERLESS_USAGE system table to track RPU consumption and estimate query costs. For example, you can calculate daily costs by aggregating charged seconds and multiplying by the RPU rate.
  • Close transactions – Make sure transactions are explicitly closed (using COMMIT or ROLLBACK) to avoid idle sessions consuming RPUs, which can lead to unnecessary charges.

The following is a practical example for a 4 RPU workgroup in US East (N. Virginia) at $0.375/RPU-hour for a scenario of a 10-minute query running daily: This is compute costs only. Primary storage capacity is billed as Redshift Managed Storage (RMS).

  • Workload duration: 10 minutes (600 seconds)
  • Cost: (600 seconds / 3600 seconds) × 4 RPUs × $0.375 = $0.25
  • Monthly cost (30 days): $0.25 × 30 = $7.50

Performance considerations

Although the 4 RPU configuration is cost-efficient, it’s designed for lighter workloads. For complex queries or datasets exceeding 32 TB, you must set up 8 RPUs to 24 RPUs to support up to 128 TB of storage. For more than 128 TB, you need 32 RPUs or more. If query performance is a priority, consider increasing the base capacity or enabling AI-driven scaling and optimization to optimize resources dynamically. Benchmark tests suggest that higher RPUs (such as 32 RPUs) significantly improve performance for complex queries. However, for simpler tasks, 4 RPUs deliver adequate throughput.

To monitor performance, use the Redshift Serverless console or CloudWatch metrics like ComputeCapacity and ComputeSeconds. The SYS_QUERY_HISTORY table can also help analyze query runtimes and identify bottlenecks.

Conclusion

Redshift Serverless with 4 RPU represents a significant step forward in making enterprise-grade analytics cheaper and accessible to organizations of different sizes, such as a startup building its first analytics system, a development team looking to optimize testing environments, or an enterprise implementing a data mesh architecture. This new configuration combines the power and flexibility of Redshift Serverless with a cost-effective entry point, so teams can start small and scale seamlessly as their needs grow. The ability to begin with minimal commitment while maintaining access to advanced features like automatic scaling, built-in security, and seamless data lake integration makes this a compelling option for modern data analytics workloads. Combined with pay-per-second billing and intelligent resource management, Redshift Serverless with 4 RPU delivers the ideal balance of cost-efficiency and performance.

To get started with cost-effective analytics, visit the AWS Management Console to create your Redshift Serverless workgroup with 4 RPUs. For more information, refer to the Amazon Redshift Serverless Management Guide or Amazon Redshift best practices. Plan your analytics budget effectively using the AWS Pricing Calculator to estimate costs based on your specific workload patterns, or contact your AWS account team to discuss your particular use case.


About the authors

Ricardo Serafim

Ricardo Serafim

Ricardo is a Senior Analytics Specialist Solutions Architect at AWS. He has been helping companies with Data Warehouse solutions since 2007.

Ashish Agrawal

Ashish Agrawal

Ashish is a Principal Product Manager with Amazon Redshift, building cloud-based data warehouses and analytics cloud services. Ashish has over 25 years of experience in IT. Ashish has expertise in data warehouses, data lakes, and platform as a service. Ashish has been a speaker at worldwide technical conferences.

Andre Hass

Andre Hass

Andre is a Senior Technical Account Manager at AWS, specialized in AWS Data Analytics workloads. With more than 20 years of experience in databases and data analytics, he helps customers optimize their data solutions and navigate complex technical challenges. When not immersed in the world of data, Andre can be found pursuing his passion for outdoor adventures. He enjoys camping, hiking, and exploring new destinations with his family on weekends or whenever an opportunity arises.

Effectively building AI agents on AWS Serverless

Post Syndicated from Anton Aleksandrov original https://aws.amazon.com/blogs/compute/effectively-building-ai-agents-on-aws-serverless/

Imagine an AI assistant that doesn’t just respond to prompts – it reasons through goals, acts, and integrates with real-time systems. This is the promise of agentic AI.

According to Gartner, by 2028 over 33% of enterprise applications will embed agentic capabilities – up from less than 1% today. While early generative AI efforts focused on GPUs and model training, agentic systems shift the focus to CPUs, orchestration, and integration with live data – the places where organizations are starting to see real return on investment (ROI).

In this post, you’ll learn how to build and run serverless AI agents on AWS using services such as Amazon Bedrock AgentCore (preview as of this post publication), AWS Lambda, and Amazon Elastic Container Service (Amazon ECS), which provide scalable compute foundations for agentic workloads. You’ll also explore architectural patterns, state management, identity, observability, and tool usage to support production-ready deployments.

Overview

Early AI assistants were stateless and reactive – each prompt processed in isolation, with no memory of prior interactions or awareness of broader context. Gradually, AI assistants became more capable by injecting system prompts, preserving conversation history, and incorporating enterprise knowledge using Retrieval-Augmented Generation (RAG), as illustrated in the following diagram.

Despite these improvements, traditional AI assistants still lacked true autonomy. They couldn’t reason through multi-step goals, make decisions on their own, or adjust workflows dynamically based on outcomes. As a result, they worked well for simpler Q&A or predefined workflows, but struggled with dynamic, more complex, real-world tasks that require planning, using external tools, and making decisions along the way.

Agentic AI systems shift from passive content generation to autonomous, goal-driven behavior. Powered by Large Language Models (LLMs) and enhanced with memory, planning, and tool use, these systems can break down complex tasks into smaller steps, reason through each step, and take real-time actions, such as calling APIs, executing tools, or interacting with live data. By referencing the LLM within a control cycle that manages context, memory, and decision-making, these systems can choose the right tools, adapt workflows, and integrate deeply into enterprise environments, with use cases ranging from travel booking and financial analysis to DevOps automation and code debugging. This is referred to as an agentic loop. In this system, the agent relies on the LLM’s reasoning output to execute tools, capture tool results, and feed these results to the LLM as updated context (as shown in the following diagram). This happens in a loop until LLM instructs the agent to return the final output to the caller.

While agentic loop is a lightweight approach to structuring these systems, other control flow paradigms, such as graph, swarm, and workflows, are also available in open-source frameworks like LangGraph.

Introducing Strands Agents SDK

Strands Agents SDK is a code-first framework to build production-ready AI agents with minimal boilerplate. It utilizes the above-mentioned agentic loop system and abstracts common challenges like memory management, tool integration, and multi-step reasoning in a lightweight, modular Python framework. Strands SDK handles state, tool orchestration, and multi-step reasoning so agents can remember past conversations, call external APIs, enforce business rules, and adapt to changing inputs. This allows you to focus on the application’s business logic.

Because agents built with Strands SDK are essentially Python apps, they’re portable and can run across different compute options, such as Bedrock AgentCore Runtime, Lambda functions, ECS tasks, or even locally. This makes Strands Agents SDK a powerful foundation for building scalable and goal-driven AI systems. The following sections assume you’re running your AI agents built with Strands Agents SDK on Lambda functions.

Building your first serverless AI agent

Imagine you’re building an AI-powered corporate travel assistant on AWS, and you have the following technical requirements:

  1. Define the system prompts, memory, and model you want to use
  2. Integrate tools for API calls, business logic, and knowledge bases
  3. Ensure authentication and observability

Strands SDK handles heavy lifting, so you can focus on building smart, responsive agents with minimal overhead. The following code snippet creates a simple agent, according to your configuration.

from strands import Agent

agent = Agent(
    system_prompt=
      """You're a travel assistant that helps 
         employees book business trips 
         according to policy.""",
    model=my_model,
    tools=[get_policies, get_hotels, get_cars, book_travel]
)

response = agent("Book me a flight to NYC next Monday.")

That’s it. Your agent now has a personality, memory, and ability to use external tools. The Agent class in the Strands SDK abstracts agentic logic, such as maintaining conversation history, handling LLM interactions, orchestrating tools and external knowledge sources, and running the full agentic loop.

Session state management

Session state management is critical for agentic workflows. It allows agents to track goals across interactions – enabling coherent conversations, retaining context, and providing personalized experiences. Without state management, each prompt is handled in isolation, making it impossible for the agent to reference prior context or track ongoing tasks. In cloud environments, where applications need to be stateless and scalable, the solution is to externalize session state to persistent storage, such as Amazon Simple Storage Service (Amazon S3). This allows any agent instance to reconstruct the conversation history on demand, delivering a seamless, stateful user experience while keeping the agentic app itself stateless for scalability and resilience.

AI agents built with Strands store conversation history in the agent.messages property (see documentation). To support stateless compute environments, you can externalize the agent state, persisting it after each interaction and restoring it before the next. This preserves continuity across invocations while keeping your agent instances stateless. In user-aware agentic applications, you want to persist state for each user, typically associated with the user’s unique ID. The following example illustrates how you can do it with the built-in S3SessionManager class when running your agent in a stateless environment such as a Lambda function:

    session_manager = S3SessionManager(
        session_id=f"session_for_user_{user.id}",
        bucket=SESSION_STORE_BUCKET_NAME,
        prefix="agent_sessions"
    )

    agent = Agent(
        session_manager=session_manager
    )

When using Bedrock AgentCore, use the fully managed, serverless AgentCore Memory primitive to manage sessions and long-term memory. It provides relevant context to models while helping agents learn from past interactions. You can make Strands’ session manager work with AgentCore Memory similar to S3SessionManager.

Authentication and authorization

For enterprise AI agents to operate safely, they must know who the user is and what they are allowed to do. This goes beyond basic identity validation – AI agents often act on behalf of users, so they might need to enforce role-based access controls, support audit, and comply with corporate policies.

AWS services like Amazon Cognito, Amazon Identity and Access Management (IAM), and Amazon API Gateway provide a solid foundation for authentication and authorization. For example, you can use Cognito to authenticate users through user pools or federated identity providers, combined with API Gateway and Lambda authorizer to validate user access permissions before forwarding requests to the agent, as shown in the preceding diagram. IAM policies define what the agent is allowed to do. After the user is both authenticated and authorized, the agent can extract the identity context, for example, from a JSON Web Token (JWT), to personalize prompts, enforce rules, or dynamically restrict actions.

The following code snippet illustrates retrieving user’s identity from the Authorization header and passing it to an agent:

def handler(event: dict, ctx):
    user_id = extract_user_id(event["headers"]["Authorization"])
    user_prompt: dict = json.loads(event["body"])["prompt"]
    agent_response = agent.prompt(user_id, user_prompt)
  
    return {
        "statusCode": 200,
        "body": json.dumps({"text": agent_response.text})
    }

The identity context can become a part of the agent’s execution loop. An agent might check the user’s department before booking travel or restrict access to sensitive tools unless the user has the appropriate permissions. By integrating authentication early, you not only enhance security, but also unlock rich personalization and audit capabilities that make agents enterprise-ready from day one.

When using Bedrock AgentCore, the AgentCore Identity primitive allows your AI agents to securely access AWS services and third-party tools either on behalf of users or as themselves with pre-authorized user consent. It provides managed OAuth 2.0 supported providers for both inbound and outbound authentication. During the preview phase, AgentCore Identity supports identity providers like Amazon Cognito, Auth0 by Okta, Microsoft Entra ID, GitHub, Google, Salesforce, and Slack. Refer to the samples for implementation details.

Building portable Strands agents on AWS

Strands Agents SDK is compute-agnostic. The agents you build are standard Python applications, which can run on any compute type.

For portability and maintainability, separate your agent’s business logic from the interface layer. By doing this, you can reuse the same core agent code across environments, whether invoked through API Gateway and Lambda functions, accessed through Application Load Balancer and Amazon ECS, running on AgentCore Runtime, or even executed locally during development, as shown in the following figure.

The following code snippets illustrate this technique.

Lambda handler code:

def handler(event: dict, ctx):
     user_id = extract_user_id(event)
     user_prompt = json.loads(event["body"])["prompt"]
     agent_response = call_agent(user_id, user_prompt)
     return {
          "statusCode":200,
          "body": json.dumps({
               "text": agent_response.mesage
          })
     }

AgentCore code:

@app.entrypoint
def invoke(payload):
     user_id = extract_user_id(payload)
     user_prompt = payload.get("prompt")
     agent_response = call_agent(user_id, user_prompt)
     return {"result": agent_response.message)

HTTP Handler code:

@app.post("/prompt")
async def prompt(request: Request, prompt_request: PromptRequest):
    user_id=extract_user_id(request)
    user_prompt = prompt_request.prompt
    agent_response = call_agent(user_id, user_prompt)
    return {"text": agent_response.message)

For local testing:

if __name__ == "__main__":
     user_id="local-testing-user"
     user_prompt="book me a trip to NYC"
     agent_response = call_agent(user_id, user_prompt)
     return agent_response.message

Agent code:

def call_agent(user_id, user_prompt):
     agent = Agent(
          system_prompt="You’re a travel agent…",
          model=my_model,
          session_manager = my_session_manager,    
      )
     agent_response = agent(user_prompt)
     return agent_response

Extending agent functionality with tools

A key strength of agentic systems is their ability to invoke tools that perform actions or retrieve real-time data, enabling agents to interact with the outside world, not just generate text. The Strands Agents SDK includes built-in tools and allows you to define your own custom tools, as either in-process Python functions or external tools accessible over HTTP using the Model Context Protocol (MCP). These tools can fetch data, call APIs, or trigger workflows, and can be registered for the agent to reason over and use during execution.

The following snippet illustrates creating an in-process tool. See the documentation for more examples.

from strands import tool 

@tool
def get_weather(city: str) -> str:
    weather = call_weather_api(city)
    return f"The current weather in {city} is {weather}"

Integrating with remote MCP servers

Model Context Protocol (MCP) is an open standard that decouples agents from tools using a client-server model. Instead of embedding tool logic directly into the agent, your agent becomes an MCP client that connects to one or more MCP servers – each exposing tools, resources, and reusable prompts.

Running remote MCP servers is especially valuable when tools span multiple business domains or are provided by third-party vendors, just like how microservices separate responsibilities across teams and systems. This separation allows each domain team to manage their own tools independently while exposing a consistent, standardized interface to agents. It also enables reuse, versioning, and centralized governance without tightly coupling logic into the agent itself. By decoupling tools from agents, MCP unlocks composability, scalability, and long-term ecosystem growth.

The following snippet illustrates configuring an MCP client to connect to a remote MCP Server, retrieving the list of tools, and integrating those tools with an agent.

mcp_client = MCPClient(lambda: streamablehttp_client(
    url=mcp_endpoint,
    headers={"Authorization": f"Bearer {token}"},
))

with mcp_client:
  tools = mcp_client.list_tools_sync()
  agent = Agent(tools=tools)

When using Bedrock AgentCore, you can operate MCP at scale through AgentCore Gateway. It provides an easy and secure way for developers to build, deploy, discover, and connect to remote tools like above at scale. With AgentCore Gateway, developers can convert APIs, Lambda functions, and existing services into Model Context Protocol (MCP)-compatible tools and make them available to agents through Gateway endpoints with just a few lines of code.

Monitoring and observability

Observability is essential when running AI agents. Beyond traditional metrics such as uptime and latency, agentic systems introduce new telemetry dimensions, such as LLM latency, token consumption, and tracing reasoning cycles. These new metrics are essential for understanding both the performance and cost of your agentic systems.

When deploying agents using AWS services such as Bedrock AgentCore, Lambda, or ECS, you inherit the built-in observability capabilities, such as seamless integration with Amazon CloudWatch for metrics, logs, and distributed tracing. This simplifies tracking invocation counts, errors, request duration, and concurrency, as shown in the following figure – essential for operating reliable and scalable agentic applications.

In addition, the Strands Agents SDK provides built-in agent observability features. It uses OpenTelemetry (OTEL) to automatically trace each agent interaction, including spans for LLM calls, tool usage, and context updates. It also exports detailed metrics such as token counts, tool execution times, and decision cycle durations. These metrics can be sent to any OTEL-compatible backend, giving you deep, real-time visibility into how your agents reason, act, and adapt. The following snippet shows built-in token usage metrics:

{
  "accumulated_usage": {
    "inputTokens": 1539,
    "outputTokens": 122,
    "totalTokens": 1661
  },
  "average_cycle_time": 0.881234884262085,
  "total_cycles": 2,
  "total_duration": 1.881234884262085,
  ... redacted ...
}

Learn more about observability and evaluation of Strands agents from this sample code.

When using Bedrock AgentCore, the AgentCore Observability primitive helps you to log and capture metrics and traceability from other AgentCore primitives like runtime, memory, and gateway, as described in this tutorial.

Security considerations

You should build secure communication and access controls layers deploying AI agents that integrate with remote MCP servers. All client-server interactions should be encrypted using TLS, ideally with mutual TLS for bidirectional authentication. Access to tools should be validated through authorization checks with fine-grained permissions to enforce least privilege access. Deploying MCP servers behind an API Gateway provides additional security layers like DDoS protection, WAF, and centralized authentication. Use API Gateway logging capabilities to capture caller identity and execution outcomes. Using trusted, versioned MCP repositories helps protect against supply chain attacks and ensures consistent tool governance across teams. Protocols such as MCP are evolving rapidly, you should always use the most recent versions to minimize potential security vulnerabilities risk.

In addition, you should leverage security best practices described in the AWS Well-Architected Framework Security Pillar, such as enforcing strict IAM role scoping, integrating with identity providers for user context, encrypting all data in transit and at rest, and using VPC endpoints and PrivateLink to limit network exposure. To protect against prompt injection attacks, sanitize inputs, and ensure you maintain comprehensive audit logs for compliance and governance.

Sample project

Follow instructions in this GitHub repo to deploy a sample project implementing the practices described in this post using the AWS Serverless compute. The repo includes a travel agent implemented with Strands Agents SDK and a remote MCP server, both running as Lambda functions.

Conclusion

Agentic AI moves beyond simple prompt-response interactions to enable dynamic, goal-driven workflows. In this post, you learned how to build scalable, production-ready agents on AWS using the Strands Agents SDK and serverless services such as Lambda and Amazon ECS.

By externalizing state, integrating authentication, and adding observability, agents can operate securely and at scale. With support for in-process and remote tools through the MCP, you can cleanly separate responsibilities and build composable, enterprise-ready systems. You can combine these patterns to deliver intelligent, adaptable AI agents that fit naturally into modern cloud and event-driven architectures.

Useful resources

To learn more about Serverless architectures see Serverless Land.

Amazon DocumentDB Serverless is now available

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/amazon-documentdb-serverless-is-now-available/

Today, we’re announcing the general availability of Amazon DocumentDB Serverless, a new configuration for Amazon DocumentDB (with MongoDB compatibility) that automatically scales compute and memory based on your application’s demand. Amazon DocumentDB Serverless simplifies database management with no upfront commitments or additional costs, offering up to 90 percent cost savings compared to provisioning for peak capacity.

With Amazon DocumentDB Serverless, you can use the same MongoDB compatible-APIs and capabilities as Amazon DocumentDB, including read replicas, Performance Insights, I/O optimized, and integrations with other Amazon Web Services (AWS) services.

Amazon DocumentDB Serverless introduces a new database configuration measured in a DocumentDB Capacity Unit (DCU), a combination of approximately 2 gibibytes (GiB) of memory, corresponding CPU, and networking. It continually tracks utilization of resources such as CPU, memory, and network coming from database operations performed by your application.

Amazon DocumentDB Serverless automatically scales DCUs up or down to meet demand without disrupting database availability. Switching from provisioned instances to serverless in an existing cluster is as straightforward as adding or changing the instance type. This transition doesn’t require any data migration. To learn more, visit How Amazon DocumentDB Serverless works.

Some key use cases and advantages of Amazon DocumentDB Serverless include:

  • Variable workloads – With Amazon DocumentDB Serverless, you can handle sudden traffic spikes such as periodic promotional events, development and testing environments, and new applications where usage might ramp up quickly. You can also build agentic AI applications that benefit from built-in vector search for Amazon DocumentDB and serverless adaptability to handle dynamically invoked agentic AI workflows.
  • Multi-tenant workloads – You can use Amazon DocumentDB Serverless to manage individual database capacity across the entire database fleet. You don’t need to manage hundreds or thousands of databases for enterprises applications or multi-tenant environments of a software as a service (SaaS) vendor.
  • Mixed-use workloads – You can balance read and write capacity in workloads that periodically experience spikes in query traffic, such as online transaction processing (OLTP) applications. By specifying promotion tiers for Amazon DocumentDB Serverless instances in a cluster, you can configure your cluster so that the reader instances can scale independently of the writer instance to handle the additional load.

For steady workloads, Amazon DocumentDB provisioned instances are more suitable. You can select an instance class that offers a predefined amount of memory, CPU power, and I/O bandwidth. If your workload changes when using provisioned instances, you should manually modify the instance class of your writer and readers. Optionally, you can add serverless instances to an existing provisioned Amazon DocumentDB cluster at any time.

Amazon DocumentDB Serverless in action
To get started with Amazon DocumentDB Serverless, go to the Amazon DocumentDB console. In the left navigation pane, choose Clusters and Create.

On the Create Amazon DocumentDB cluster page, choose Instance-based cluster type and then Serverless instance configuration. You can choose minimum and maximum capacity DCUs. Amazon DocumentDB Serverless is supported starting with Amazon DocumentDB 5.0.0 and higher with a capacity range of 0.5–256 DCUs.

If you use features such as auditing and Performance Insights, consider adding DCUs for each feature. To learn more, visit Amazon DocumentDB Serverless scaling configuration.

To add a serverless instance to an existing provisioned cluster, choose Add instances on the Actions menu when you choose the provisioned cluster. If you use a cluster with an earlier version such as 3.6 or 4.0, you should first upgrade the cluster to the supported engine version (5.0).

On the Add instances page, choose Serverless in the DB instance class section for each new serverless instance you want to create. To add another instance, choose Add instance and continue adding instances until you have reached the desired number of new instances. Choose Create.

You can perform a failover operation to make a DocumentDB Serverless instance the cluster writer. Also, you can convert any remaining provisioned Amazon DocumentDB instances to DocumentDB Serverless instances by changing an instance’s class or removing them from the cluster by deleting an Amazon DocumentDB instance.

Now, you can connect to your Amazon DocumentDB cluster using AWS CloudShell. Choose Connect to cluster, and you can see the AWS CloudShell Run command screen. Enter a unique name in New environment name and choose Create and run.

When prompted, enter the password for the Amazon DocumentDB cluster. You’re successfully connected to your Amazon DocumentDB cluster, and you can run a few queries to get familiar with using a document database.

To learn more, visit Creating a cluster that uses Amazon DocumentDB Serverless and Managing Amazon DocumentDB Serverless in the AWS documentation.

Now available
Amazon DocumentDB Serverless is now available starting with Amazon DocumentDB 5.0 for both new and existing clusters. You only pay a flat rate per second of DCU usage. To learn more about pricing details and Regional availability, visit the Amazon DocumentDB pricing page.

Give these new features a try in the Amazon DocumentDB console and send feedback to AWS re:Post for Amazon DocumentDB or through your usual AWS Support contacts.

— Channy

How Zapier runs isolated tasks on AWS Lambda and upgrades functions at scale

Post Syndicated from Anton Aleksandrov original https://aws.amazon.com/blogs/architecture/how-zapier-runs-isolated-tasks-on-aws-lambda-and-upgrades-functions-at-scale/

Zapier is a leading no-code automation provider whose customers use their solution to automate workflows and move data across over 8,000 applications such as Slack, Salesforce, Asana, and Dropbox. Zapier runs these automations through integrations called Zaps, which are implemented using a serverless architecture running on Amazon Web Services (AWS). Each Zap is powered by an AWS Lambda function.

In this post, you’ll learn how Zapier has built their serverless architecture focusing on three key aspects: using Lambda functions to build isolated Zaps, operating over a hundred thousand Lambda functions through Zapier’s control plane infrastructure, and enhancing security posture while reducing maintenance efforts by introducing automated function upgrades and cleanup workflows into their platform architecture.

Architecting a secure and isolated runtime environment

Zaps created by Zapier’s users implement tenant-specific business logic, hence they require cross-tenant compute isolation. Code implementing one Zap can’t share an execution environment with code implementing another Zap. Moreover, the same Zap type used by two different tenants can’t share execution environments as well.

To achieve the required level of isolation, Zapier’s engineering team adopted AWS Lambda, a serverless compute service that runs code in response to events and automatically manages cloud compute resources. Minimal operational overhead, built-in high availability, automated scaling, high level of isolation, and pay-per-use model made Lambda a great fit for this use case. Currently, Zapier’s architecture is running over a hundred thousand Lambda functions to support their customer’s integration workflows.

Because they’re powered by the open source Firecracker microVMs, each function is completely isolated from the others. Moreover, each execution environment belonging to the same function (sometimes referred to as function instances) is also isolated from other execution environments. The following architecture topology diagram uses red lines to represent isolation boundaries. Each execution environment of every function is isolated from its peers and is getting its own virtual resources such as disk, memory, and CPU. For more details, read Security in AWS Lambda.

Isolation boundary

Zapier’s control plane is architected using Amazon Elastic Kubernetes Service (Amazon EKS). A designated database is used to maintain the up-to-date function inventory. Whenever a user creates a new Zap, the control plane creates a corresponding Lambda function and stores a reference in the inventory database. When a Zap is triggered, the control plane retrieves information about a relevant Lambda function and invokes it to facilitate the integration workflow, as illustrated in the following diagram.

Control and Data planes

Understanding the runtime deprecation process

When building architectures using the traditional non-serverless compute, cloud engineers are the ones responsible for keeping operating systems and software on their compute instances up to date and applying security and maintenance patches. With serverless architectures and Lambda functions, security patches and minor runtime upgrades are handled by AWS automatically, which means customers can focus on delivering business value instead of the undifferentiated heavy lifting of infrastructure management.

When a major Lambda managed runtime version reaches end-of-life, AWS initiates a deprecation process through the AWS Health Dashboard and direct email communications to affected customers. Because deprecated runtimes eventually lose access to security updates and support, organizations must upgrade to supported runtime versions to avoid potential security risks. Read more about the shared responsibility model, runtime use after deprecation, and receiving runtime deprecation notifications.

As Zapier’s user base and architectural complexity – and consequently the number of Zaps – were growing, keeping all functions on the most up-to-date major runtime versions became a laborious task. Top contributing factors were:

  • High number of functions. At its peak, the Zapier platform was running Zaps using hundreds of thousands of unique Lambda functions. Approximately 35% of these functions were using a runtime that was scheduled for deprecation in the next 12 months.
  • Zapier architected their data plane environment to be ephemeral – the control plane creates and deletes Lambda functions on demand and manages their lifecycle dynamically. Identifying a specific owner for each affected function wasn’t always straightforward.
  • Security is paramount at Zapier and upgrading affected functions runtime prior to the deprecation date was an absolute must. At no point could Zapier functions use runtimes after their deprecation date. This was a task which required extra resources.
  • The upgrade process shouldn’t have had any impact on the end customer experience. At no point should customer experience be affected.

With a short runway, high-volume workload, and the strict requirements of not impacting customer experience, Zapier’s Platform Engineering team took on this challenge of maintaining high security posture in their platform architecture.

Applying the solution

The solution had three work streams:

  1. Reducing the risk by analyzing the architecture and identifying and cleaning up unused functions.
  2. Prioritizing upgrades by identifying the most critical and impactful functions.
  3. Empowering engineering teams with automated tools and knowledge to streamline the upgrade process in future.

Identify and clean up unused functions

The first step in streamlining the upgrade process was identifying and removing unused functions. This reduced the total number of functions in Zapier’s architecture that required upgrades, eliminating unnecessary work for the team.

Zapier started by augmenting the function inventory with runtime information using AWS Trusted Advisor and Amazon Cloud Intelligence Trusted Advisor dashboards, as illustrated in the following diagram.

Gathering data

This meant the team could build a detailed inventory of functions that were running on soon-to-be deprecated runtimes. Using Amazon CloudWatch, Zapier’s platform team started to monitor metrics such as number of invocations. They identified which functions were active, which functions weren’t used for an extended period, and which functions didn’t have an active owner and could be removed.

One of the primary mechanisms for ownership validation within the organization was using resource tags. Functions that were active, but didn’t have clear ownership, were flagged for additional review before removal. Functions that were confirmed as unused or didn’t have an active owner were marked for deletion. Removing such functions allowed Zapier to significantly simplify their architecture and reduce the number of functions that had to be upgraded.

Prioritizing upgrades

With a smaller volume of functions to upgrade, Zapier’s platform team prioritized function upgrades based on usage patterns, criticality, and potential customer impact. Three primary prioritization categories were:

  • Customer-facing functions – Any functions directly involved in executing user Zaps were marked as high priority. These had to be upgraded first to avoid service disruptions.
  • Backend infrastructure functions – Internal functions that supported system operations were evaluated based on their importance to platform stability.
  • High-volume functions – Functions with the highest execution frequency were prioritized because upgrading them would have the greatest impact on reducing operational risk.

Using these factors, Zapier’s platform team has created an upgrade roadmap, ensuring that critical assets were addressed first while minimizing potential disruptions.

Refer to Retrieve data about Lambda functions that use a deprecated runtime in the Lambda Developer Guide to learn how to identify most commonly and most frequently used Lambda functions in your serverless architecture.

Empowering engineering teams with automated tools and knowledge

To ensure a smooth and efficient upgrade process across their serverless architecture, Zapier’s team empowered engineering teams with clear guidelines and automated solutions. The platform incorporated two main approaches: Terraform-managed functions and a custom-built Lambda runtime canary tool. Implementing and adopting these tools and practices resulted in reducing the number of functions using soon-to-be deprecated runtimes by 95%.

For functions managed through infrastructure-as-code (IaC), Zapier’s team developed standardized Terraform modules that specified supported runtime versions. Development teams implemented these modules in their configurations:

resource "aws_lambda_function" "example" {
    runtime = "python3.13"  # Updated to supported runtime
}

After applying the new module version, teams validated changes by testing the new runtime in staging environments and monitoring Terraform plan outputs to ensure proper runtime version updates.

To efficiently manage most Lambda functions in their architecture, Zapier developed the Lambda runtime canary tool suite. Using this solution, they automated the runtime upgrade process for thousands of active Lambda functions with minimal manual intervention. The tool suite implements several key features:

  • Architected for gradual traffic shifting with the Lambda built-in routing mechanism through function version and aliasing. The tool can gradually shift traffic distribution from an old to a new function version. During this gradual traffic shift, the system monitors CloudWatch metrics for errors and automatically rolls back if error rates exceed acceptable thresholds.
  • Optimistic upgrade strategy implements direct upgrades for infrequently used functions using a flag value stored in a cache to detect potential issues during the first post-upgrade invocation. If this invocation fails, the control plane retries it using the previous function version. If the retried invocation succeeds, Zapier’s control plane initiates a rollback, assuming the error is most likely due to the runtime upgrade. After rollback, it will log the error and alert relevant stakeholders.
  • Integration with existing infrastructure uses an administrative interface and task queue for automated traffic shifting. A database ledger maintains tracking of function states and rollback information.
  • Operational controls provide manual rollback capabilities and implement centralized control switches for process management. After a function was upgraded to a new runtime and no rollback activity was detected within a set time period, an automated pruning task cleans up older versions.

Zapier’s Lambda canary tool, through its integration of gradual traffic shifting, real-time CloudWatch monitoring, and automated rollback mechanisms, established a sustainable framework for managing runtime upgrades across their serverless architecture. This approach not only automated the upgrade process and minimized operational risks but also created a scalable solution that provides continuous runtime upgrades, preventing the use of deprecated runtimes at any point. By allowing continuous function runtime updates with minimal disruption to end user experience, Zapier maintains security and stability while requiring minimal manual intervention. This framework efficiently manages their growing serverless infrastructure, providing both security and operational efficiency for future runtime updates.

Conclusion

In this post, you’ve learned how Zapier architected their software-as-a-service (SaaS) platform to provide secure, isolated execution environments using AWS Lambda and Amazon EKS, enabling their customers to create hundreds of thousands of Zaps. You’ve learned how Zapier’s team implemented the function runtime upgrade process at scale and reduced the number of functions running on soon-to-be deprecated runtimes by 95%. You’ve seen best practices that were established and techniques that helped Zapier to keep high security posture without impacting customer experience.

Use the following links to learn more about Lambda runtimes and upgrading your functions to the latest runtime versions:


About the authors

Implementing message prioritization with quorum queues on Amazon MQ for RabbitMQ

Post Syndicated from Akhil Melakunta original https://aws.amazon.com/blogs/compute/implementing-message-prioritization-with-quorum-queues-on-amazon-mq-for-rabbitmq/

Quorum queues are now available on Amazon MQ for RabbitMQ from version 3.13. Quorum queues are a replicated First-In, First-Out (FIFO) queue type that uses the Raft consensus algorithm to maintain data consistency. Quorum queues on RabbitMQ version 3.13 lack one key feature compared to classic queues: message prioritization. However, RabbitMQ version 4.0 introduced support for message priority, which behaves differently than classic queue message priorities. Migrating applications from classic queues with message priority to quorum queues on Amazon MQ for RabbitMQ presents challenges for customers. This post describes the different approaches to implementing message prioritization in quorum queues in Amazon MQ for RabbitMQ.

Amazon MQ is a managed message broker service for Apache ActiveMQ and RabbitMQ that simplifies setting up and operating message brokers on AWS.

Why message prioritization matters

Modern messaging systems require handling messages differently, depending on the business priority. Some messages are more time-sensitive or critical than others and prioritizing them can enhance the efficiency and responsiveness of applications. Message prioritization allows certain messages to be processed before others, aligning with business priorities and helping to ensure that high-value or time-critical messages receive the attention they need.

Message prioritization addresses critical business challenges across multiple industries. In insurance companies, it can expedite urgent claim processing by prioritizing high-priority messages over routine policy updates, reducing settlement times. Automotive manufacturers can make sure that critical production line alerts and safety notifications take precedence over standard telemetry data, preventing costly downtime. Energy utilities can prioritize real-time grid stability alerts and outage notifications, enabling faster responses to potential blackouts. By implementing message priority, industries can direct immediate attention to time-sensitive operations while efficiently managing routine processes within existing infrastructure. By using this approach to transform their communication strategies, organizations can respond more quickly and effectively to critical events.

Classic queues compared to quorum queues message prioritization

In this section, explore the fundamental differences between classic queues and quorum queues when it comes to message prioritization capabilities. Examine how each queue type handles message priority, the built-in features available, and key considerations.

Message prioritization with classic queues

In classic queues, RabbitMQ supports message priorities ranging from 1 to 255, with 1 being the lowest priority and 255 being the highest. However, it’s generally recommended to use a smaller range (for example, 1–5) for better performance, because RabbitMQ needs to maintain an internal sub-queue for each priority from 1 up to the maximum value configured for a given queue. A wider priority range adds more CPU and memory cost, which can impact broker performance.

Priority queue behavior in classic queues:

  • Classic queues require x-max-priority argument to define the maximum number of priorities for a given queue
  • A procedure sends a message with a priority property value
  • Consumers don’t need special configuration to handle priorities
  • Messages with higher priority are delivered before messages with lower priority
  • Within the same priority level, messages are delivered in FIFO order
  • Messages without a priority property are treated as if their priority is lowest
  • Messages with a priority that is higher than the queue’s maximum are treated as if they were published with the maximum priority

Example Python code for classic queue implementation with message priority:

#!/usr/bin/env python
import pika
import ssl
# Set up SSL context for secure connection
context = ssl.SSLContext(ssl.PROTOCOL_TLSv1_2)
# Define credentials
credentials = pika.PlainCredentials('username', 'password') # Replace with actual credentials
# Set up connection parameters for Amazon MQ RabbitMQ broker
connection_parameters = pika.ConnectionParameters(
    host='b-example.mq.us-west-2.on.aws', # Replace with actual broker endpoint
    port=5671,
    credentials=credentials,
    ssl_options=pika.SSLOptions(context)
)
# Establish connection and create a channel
connection = pika.BlockingConnection(connection_parameters)
channel = connection.channel()
# Declare a direct exchange
# - direct exchanges route messages based on routing key
channel.exchange_declare(
    exchange='priority_exchange',
    exchange_type='direct',
)
# Declare a priority queue
# - x-max-priority=5 sets maximum priority level (0-5)
# - x-queue-type=classic specifies classic queue implementation
channel.queue_declare(
    queue='classic_priority_queue',
    arguments={
        'x-max-priority': 5,
        'x-queue-type': "classic"
    }
)
# Bind queue to exchange with routing key
# - This connects the queue to the exchange
# - Messages sent to the exchange with matching routing key will be routed to this queue
channel.queue_bind(
    queue='classic_priority_queue',
    exchange='priority_exchange',
    routing_key='priority_queue'
)
# Publish messages with different priorities
# Low priority message (priority=1)
channel.basic_publish(
    exchange='priority_exchange',
    routing_key='priority_queue',
    body='Low priority message',
    properties=pika.BasicProperties(priority=1)
)
print(" [x] Sent 'Low priority message'")
# Medium priority message (priority=2)
channel.basic_publish(
    exchange='priority_exchange',
    routing_key='priority_queue',
    body='Medium priority message',
    properties=pika.BasicProperties(priority=2)
)
print(" [x] Sent 'Medium priority message'")
# High priority message (priority=5)
channel.basic_publish(
    exchange='priority_exchange',
    routing_key='priority_queue',
    body='High priority message',
    properties=pika.BasicProperties(priority=5)
)
print(" [x] Sent 'High priority message'")
# Close the connection
connection.close()

The preceding code demonstrates message prioritization in RabbitMQ using a classic queue with built-in priority handling. The implementation connects to a RabbitMQ broker using the Python Pika library and declares a direct exchange, a classic queue with a maximum priority level of 5. Messages are then published to this single queue with explicitly assigned priority values (1 for low, 2 for medium, and 5 for high priority). When consumers fetch messages from this queue, RabbitMQ will deliver higher priority messages first.

Message prioritization with quorum queues

Unlike classic queues, quorum queues in Rabbit MQ 3.13 don’t support message prioritization natively. However, there are effective patterns that you can implement to achieve message priority with Quorum queues.

Using separate queues for different priorities

A straightforward method is to create multiple quorum queues, each dedicated to different priority levels. For example, you might have a high-priority queue and a low-priority queue. Using RabbitMQ exchange and binding key route messages to the appropriate queues based on their priority, allowing the system to process high-priority messages more promptly, as shown in the following figure.

Example to implement priority handling using separate quorum queues:

#!/usr/bin/env python
import pika
import ssl
# Set up SSL context for secure connection
context = ssl.SSLContext(ssl.PROTOCOL_TLSv1_2)
# Define credentials
credentials = pika.PlainCredentials('username', 'password') #Replace with actual credentials
# Set up connection parameters for Amazon MQ RabbitMQ broker
connection_parameters = pika.ConnectionParameters(
    host='b-example.mq.us-west-2.on.aws',
    port=5671,
    credentials=credentials,
    ssl_options=pika.SSLOptions(context)
)
# Establish connection and create a channel
connection = pika.BlockingConnection(connection_parameters)
channel = connection.channel()
# Declare a direct exchange
# - Direct exchanges route messages based on routing key
channel.exchange_declare(
    exchange='priority_exchange_qq',
    exchange_type='direct'
)
# Create separate quorum queues for different priority levels
# Low priority queue
channel.queue_declare(
    queue='low_priority_queue',
    durable=True,
    arguments={
        'x-queue-type': "quorum" 
    }
)
# Bind the low priority queue to the exchange with a specific routing key
# - This creates a rule that messages sent to 'priority_exchange' with routing_key='low_priority_1'
# - will be routed to the 'low_priority_queue'
channel.queue_bind(
    queue='low_priority_queue',
    exchange='priority_exchange_qq',
    routing_key='low_priority_1'
)
# Medium priority queue
channel.queue_declare(
    queue='medium_priority_queue',
    durable=True,
    arguments={
        'x-queue-type': "quorum" 
    }
)
# Bind the medium priority queue to the exchange with a specific routing key
# - Messages with routing_key='medium_priority_2' will be directed to the 'medium_priority_queue'
channel.queue_bind(
    queue='medium_priority_queue',
    exchange='priority_exchange_qq',
    routing_key='medium_priority_2'
)
# High priority queue
channel.queue_declare(
    queue='high_priority_queue',
    durable=True,
    arguments={
        'x-queue-type': "quorum" 
    }
)
# Bind the high priority queue to the exchange with a specific routing key
# - Messages with routing_key='high_priority_2' will be directed to the 'high_priority_queue'
channel.queue_bind(
    queue='high_priority_queue',
    exchange='priority_exchange_qq',
    routing_key='high_priority_5'
)
# Publish messages to different priority queues
print(" [x] Publishing messages to different priority queues")
# Low priority message
channel.basic_publish(
    exchange='priority_exchange_qq',  
    routing_key='low_priority_1',
    body='Low priority message'
)
print(" [x] Sent 'Low priority message'")
# Medium priority message
channel.basic_publish(
    exchange='priority_exchange_qq', 
    routing_key='medium_priority_2',
    body='Medium priority message'
)
print(" [x] Sent 'Medium priority message'")
# High priority message
channel.basic_publish(
    exchange='priority_exchange_qq', 
    routing_key='high_priority_5',
    body='High priority message'
)
print(" [x] Sent 'High priority message'")
# Close the connection
connection.close()
print(" [x] Connection closed")

The preceding code demonstrates a message prioritization approach in RabbitMQ using separate quorum queues for different priority levels (low, medium, and high). The implementation uses the Python Pika library to connect to a RabbitMQ server, a direct exchange and three separate quorum queues for different priority levels, and publish messages to different routing keys with different priority.

Custom priority logic on consumers

Implement custom logic within your application to handle messages based on their priority. For example, you can use headers or metadata to determine the priority of a message and then use this information to route messages to different queues or handle them in a specific order.

Higher priority queues should use more consumers or consumers with higher resources allocated to process messages more quickly than lower priority queues. Use the basic.qos (prefetch) method in manual acknowledgement mode on your consumers to limit the number of messages that can be out for delivery at any time and allow messages to be prioritized. basic.qos is a value a consumer sets when connecting to a queue. It indicates how many messages the consumer can handle at one time. This method is shown in the following figure.

Note: This solution implements message priority on a best-effort basis. There is a possibility that low and medium priority messages may be processed before high priority messages.

Conclusion

Message prioritization in RabbitMQ brokers on Amazon MQ has different considerations for classic and quorum queues. Using quorum queues requires a thoughtful approach because of the lack of native support for message proritization in RabbitMQ. By employing separate queues and custom logic, you can achieve effective prioritization while maintaining the high availability and consistency that quorum queues offer. Embrace these strategies to optimize your messaging infrastructure, enhance application responsiveness, and make sure that critical messages are processed in a timely manner.

We recommend that you adopt quorum queues as the preferred replicated queue type on RabbitMQ 3.13 brokers. For more details, see Amazon MQ documentation. For more information, see quorum queues.

To learn more, see Amazon MQ for Rabbit MQ.

Building resilient multi-tenant systems with Amazon SQS fair queues

Post Syndicated from Maximilian Schellhorn original https://aws.amazon.com/blogs/compute/building-resilient-multi-tenant-systems-with-amazon-sqs-fair-queues/

Today, AWS introduced Amazon Simple Queue Service (Amazon SQS) fair queues, a new feature that mitigates noisy neighbor impact in multi-tenant systems. With fair queues, your applications become more resilient and easier to operate, reducing operational overhead while improving quality of service for your customers.

In distributed architectures, message queues have become the backbone of resilient system design. They act as buffers between components, allowing services to process work asynchronously and at their own pace. When a sudden traffic spike hits your application, queues prevent cascading failures by buffering work and ensuring that downstream services aren’t overwhelmed. Amazon SQS has long been a go-to solution for developers building scalable applications because it’s a fully managed serverless solution that can seamlessly scale to ingest millions of messages per second.

In this post, you learn how to use Amazon SQS fair queues and understand their inner workings through a practical example.

Overview

Many modern applications follow a multi-tenant architecture, where a single application instance serves multiple tenants. A tenant is any entity that shares resources with others. It could be a customer, client application, or request type. This approach reduces operational costs and simplifies maintenance through efficient resource utilization. One example of such shared resources are queues and their associated consumer capacity.

However, multi-tenant systems face challenges when one tenant becomes a noisy neighbor. This tenant impacts others by overutilizing your system’s resources. With queues, this tenant causes a backlog by sending a large volume of messages or by requiring longer processing time. Regular queues deliver older messages first, which increases message dwell time for all tenants in such scenarios. This makes it difficult to maintain quality of service and forces teams to over-provision resources or build complex custom solutions.

Amazon SQS fair queues help maintain low dwell time for other tenants when there is a noisy neighbor. This happens transparently without requiring changes to your existing message processing logic. You define what constitutes a tenant in your system, and Amazon SQS handles the complex orchestration of mitigating noisy neighbor impact.

How it works

Amazon SQS continually monitors the distribution of messages received but not yet deleted (in-flight) by consumers across all tenants. When the system detects an imbalance:

  1. It identifies the noisy tenant, the one causing the queue to build a backlog.
  2. It automatically adjusts message delivery order to prioritize messages belonging to quiet (non-noisy) tenants.
  3. It maintains overall queue throughput.

Consider the following example that consists of a multi-tenant queue and four different tenants (A, B, C, and D).

In the steady state condition, the queue has no backlog, and in-flight messages are evenly distributed among tenants. All messages are consumed immediately when they land in the queue. The dwell time of messages is low for all tenants. Notice that not all consumer capacity is fully utilized in this steady state. The steady state condition is illustrated in the following diagram.

Figure 1: A multi-tenant queue in steady state condition

Figure 1: A multi-tenant queue in steady state condition

Now consider a noisy tenant scenario in which the number of messages of tenant A increases significantly and creates a backlog in the queue. Consumers are busy processing the messages mostly from tenant A, and messages from other tenants are waiting in the backlog, leading to a higher dwell time for all tenants. This noisy tenant scenario is illustrated in the following screenshot.

Figure 2: A multi-tenant queue with a noisy tenant

Figure 2: A multi-tenant queue with a noisy tenant

When a single tenant starts to occupy a significant portion of consumer resources, Amazon SQS fair queues considers this tenant as a noisy neighbor and prioritizes returning messages belonging to other tenants. This prioritization helps maintain low dwell times for quiet tenants (B, C, D), while the dwell time for tenant A’s messages will be elevated until the queue backlog is consumed—but without impacting other tenants. Fair queues are illustrated in the following diagram.

Figure 3: A multi-tenant queue with fair queues

Figure 3: A multi-tenant queue with fair queues

Amazon SQS doesn’t limit the consumption rate per tenant. Consumers can receive messages from noisy neighbor tenants when there is consumer capacity and the queue has no other messages to return. Like Amazon SQS standard queues, fair queues allow virtually unlimited throughput, and there are no limits on the number of tenants you can have in your queue.

How to use

The following is a quick overview of how to get started with Amazon SQS fair queues in your applications. See the feature documentation for a detailed walkthrough. These are the high-level steps the walkthrough follows:

  1. Enable Amazon SQS fair queues by adding a tenant identifier (MessageGroupId) to your messages
  2. Configure Amazon CloudWatch metrics to monitor Amazon SQS fair queues behavior
  3. You can use the example application to observe the Amazon SQS fair queues behavior with varying message volumes

Enable Amazon SQS fair queues by adding a tenant identifier (MessageGroupId) to your messages

Your message producers can add a tenant identifier by setting a MessageGroupId on an outgoing message:

// Send message with tenant identifier
SendMessageRequest request = new SendMessageRequest()
    .withQueueUrl(queueUrl)
    .withMessageBody(messageBody)
    .withMessageGroupId("tenant-123");  // Tenant identifier
sqs.sendMessage(request);

The new fairness capability will be applied automatically in all Amazon SQS standard queues for messages with the MessageGroupId property. It’s important to mention that it doesn’t require any change in the consumer code. It has no impact on API latency and doesn’t come with any throughput limitations.

Configure Amazon CloudWatch metrics to monitor Amazon SQS fair queues behavior

You can monitor Amazon SQS fair queues with Amazon CloudWatch metrics. The following terms are important in this context:

  • Noisy groups – A noisy message group represents a noisy neighbor tenant of a multi-tenant queue.
  • Quiet groups – Message groups excluding noisy groups.

When you use fair queues, Amazon SQS now emits the following additional metrics:

  • ApproximateNumberOfNoisyGroups
  • ApproximateNumberOfMessagesVisibleInQuietGroups
  • ApproximateNumberOfMessagesNotVisibleInQuietGroups
  • ApproximateNumberOfMessagesDelayedInQuietGroups
  • ApproximateAgeOfOldestMessageInQuietGroups

The new ApproximateNumberOfNoisyGroups metric gives the number of message groups (tenants) that are considered noisy in a fair queue. This metric helps identify the number of potential noisy neighbors in multi-tenant environments by tracking message groups consuming disproportionate resources. Use this metric to set alarms that trigger when the number of noisy groups exceeds your acceptable threshold, indicating potential queue fairness issues.

Amazon SQS already provides several standard queue-level metrics that offer approximate insights into the queue’s state, message processing, and potential bottlenecks. These metrics look at all messages in a queue. With fair queues, there’s a new set of four equivalent metrics, shown in the preceding list, that allow the exclusion of messages from noisy neighbor groups and target only quiet groups (non-noisy tenants). Hence, they all have the InQuietGroups suffix.

To monitor the effect of Amazon SQS fair queues you can compare metrics that have the InQuietGroups suffix with standard queue-level metrics. During traffic surges for a specific tenant, the general queue-level metrics might reveal increasing backlogs or older message ages. However, looking at the quiet groups in isolation, you can identify that most non-noisy message groups or tenants aren’t impacted, and you can estimate the total number of impacted message groups.

The following graph shows how the standard queue backlog metric (ApproximateNumberOfMessagesVisible) increases due to a noisy tenant while the backlog for non-noisy tenants (ApproximateNumberOfMessagesVisibleInQuietGroups) remains low.

Figure 4: Queue backlog for noisy and quiet groups

Figure 4: Queue backlog for noisy and quiet groups

While these new metrics provide a good overview of Amazon SQS fair queues behavior, it can be beneficial to understand which specific tenant is causing the load. Use Amazon CloudWatch Contributor Insights to see metrics about the top-N contributors, the total number of unique contributors, and their usage. This is especially helpful in scenarios where you’re dealing with thousands of tenants that would otherwise lead to high-cardinality data (and cost) when emitting traditional metrics. The following screenshot shows an example of a Contributor Insights dashboard on the AWS console that visualizes the top 10 contributors based on MessageGroupId.

Figure 5: Container Insights ReceivedMessagesPerMessageGroupId dashboard

Figure 5: Container Insights ReceivedMessagesPerMessageGroupId dashboard

Contributor Insights creates these metrics based on data from your application log output. Let your code log the number of messages being processed, and the corresponding MessageGroupId within your application. You can find a full example in the sample application in the next section.

Example application

To make it even more straightforward to get started, we’ve prepared an example application that you can use to observe the Amazon SQS fair queues behavior with varying message volumes. You can find the source code repository, infrastructure as code (IaC), and the instructions to run the sample on the sqs-fair-queues repository on GitHub.

The example application includes a load generator to simulate multi-tenant traffic and provides an Amazon CloudWatch dashboard that displays the most important metrics to visualize fair queue behavior. The following screenshot shows an example of the dashboard.


Figure 6: CloudWatch FairQueuesDashboard

Conclusion

Amazon SQS fair queues automatically mitigates the noisy neighbor impact in multi-tenant queues. Even when one tenant generates high message volumes or requires longer processing times (that is, becomes a noisy neighbor), the feature maintains consistent message dwell times for other tenants. When you add a tenant identifier to your messages, Amazon SQS fair queues will automatically detect and mitigate noisy neighbor impact, providing fair access to the queue for other tenants.

We recommend reviewing the Amazon SQS Developer Guide to get started and exploring the sample applications to test the behavior with varying message volumes.

Simplify serverless development with console to IDE and remote debugging for AWS Lambda

Post Syndicated from Micah Walter original https://aws.amazon.com/blogs/aws/simplify-serverless-development-with-console-to-ide-and-remote-debugging-for-aws-lambda/

Today, we’re announcing two significant enhancements to AWS Lambda that make it easier than ever for developers to build and debug serverless applications in their local development environments: console to IDE integration and remote debugging. These new capabilities build upon our recent improvements to the Lambda development experience, including the enhanced in-console editing experience and the improved local integrated development environment (IDE) experience launched in late 2024.

When building serverless applications, developers typically focus on two areas to streamline their workflow: local development environment setup and cloud debugging capabilities. While developers can bring functions from the console to their IDE, they’re looking for ways to make this process more efficient. Additionally, as functions interact with various AWS services in the cloud, developers want enhanced debugging capabilities to identify and resolve issues earlier in the development cycle, reducing their reliance on local emulation and helping them optimize their development workflow.

Console to IDE integration

To address the first challenge, we’re introducing console to IDE integration, which streamlines the workflow from the AWS Management Console to Visual Studio Code (VS Code). This new capability adds an Open in Visual Studio Code button to the Lambda console, enabling developers to quickly move from viewing their function in the browser to editing it in their IDE, eliminating the time-consuming setup process for local development environments.

The console to IDE integration automatically handles the setup process, checking for VS Code installation and the AWS Toolkit for VS Code. For developers that have everything already configured, choosing the button immediately opens their function code in VS Code, so they can continue editing and deploy changes back to Lambda in seconds. If VS Code isn’t installed, it directs developers to the download page, and if the AWS Toolkit is missing, it prompts for installation.

To use console to IDE, look for the Open in VS Code button in either the Getting Started popup after creating a new function or the Code tab of existing Lambda functions. After selecting, VS Code opens automatically (installing AWS Toolkit if needed). Unlike the console environment, you now have access to a full development environment with integrated terminal – a significant improvement for developers who need to manage packages (npm install, pip install), run tests, or use development tools like linters and formatters. You can edit code, add new files/folders, and any changes you make will trigger an automatic deploy prompt. When you choose to deploy, the AWS Toolkit automatically deploys your function to your AWS account.

Screenshot showing Console to IDE

Remote debugging

Once developers have their functions in their IDE, they can use remote debugging to debug Lambda functions deployed in their AWS account directly from VS Code. The key benefit of remote debugging is that it allows developers to debug functions running in the cloud while integrated with other AWS services, enabling faster and more reliable development.

With remote debugging, developers can debug their functions with complete access to Amazon Virtual Private Cloud (VPC) resources and AWS Identity and Access Management (AWS IAM) roles, eliminating the gap between local development and cloud execution. For example, when debugging a Lambda function that interacts with an Amazon Relational Database Service (Amazon RDS) database in a VPC, developers can now debug the execution environment of the function running in the cloud within seconds, rather than spending time setting up a local environment that might not match production.

Getting started with remote debugging is straightforward. Developers can select a Lambda function in VS Code and enable debugging in seconds. AWS Toolkit for VS Code automatically downloads the function code, establishes a secure debugging connection, and enables breakpoint setting. When debugging is complete, AWS Toolkit for VS Code automatically cleans up the debugging configuration to prevent any impact on production traffic.

Let’s try it out

To take remote debugging for a spin, I chose to start with a basic “hello world” example function, written in Python. I had previously created the function using the AWS Management Console for AWS Lambda. Using the AWS Toolkit for VS Code, I can navigate to my function in the Explorer pane. Hovering over my function, I can right-click (ctrl-click in Windows) to download the code to my local machine to edit the code in my IDE. Saving the file will ask me to decide if I want to deploy the latest changes to Lambda.

Screenshot view of the Lambda Debugger in VS Code

From here, I can select the play icon to open the Remote invoke configuration page for my function. This dialog will now display a Remote debugging option, which I configure to point at my local copy of my function handler code. Before choosing Remote invoke, I can set breakpoints on the left anywhere I want my code to pause for inspection.

My code will be running in the cloud after it’s invoked, and I can monitor its status in real time in VS Code. In the following screenshot, you can see I’ve set a breakpoint at the print statement. My function will pause execution at this point in my code, and I can inspect things like local variable values before either continuing to the next breakpoint or stepping into the code line by line.

Here, you can see that I’ve chosen to step into the code, and as I go through it line by line, I can see the context and local and global variables displayed on the left side of the IDE. Additionally, I can follow the logs in the Output tab at the bottom of the IDE. As I step through, I’ll see any log messages or output messages from the execution of my function in real time.

Enhanced development workflow

These new capabilities work together to create a more streamlined development experience. Developers can start in the console, quickly transition to VS Code using the console to IDE integration, and then use remote debugging to debug their functions running in the cloud. This workflow eliminates the need to switch between multiple tools and environments, helping developers identify and fix issues faster.

Now available

You can start using these new features through the AWS Management Console and VS Code with the AWS Toolkit for VS Code (v3.69.0 or later) installed. Console to IDE integration is available in all commercial AWS Regions where Lambda is available, except AWS GovCloud (US) Regions. Learn more about it in Lambda and AWS Toolkit for VS Code documentation. To learn more about remote debugging capability, including AWS Regions it is available in, visit the AWS Toolkit for VS Code and Lambda documentation.

Console to IDE and remote debugging are available to you at no additional cost. With remote debugging, you pay only for the standard Lambda execution costs during debugging sessions. Remote debugging will support Python, Node.js, and Java runtimes at launch, with plans to expand support to additional runtimes in the future.

These enhancements represent a significant step forward in simplifying the serverless development experience, which means developers can build and debug Lambda functions more efficiently than ever before.