Tag Archives: serverless

Infrastructure as code translation for serverless using AI code assistants

Post Syndicated from Debasis Rath original https://aws.amazon.com/blogs/compute/infrastructure-as-code-translation-for-serverless-using-ai-code-assistants/

Serverless applications commonly use infrastructure as code (IaC) frameworks to define and manage their cloud resources. Teams choose different IaC tools based on their skills, existing tooling, or compliance needs. As applications grow, the need to shift between IaC formats may arise to adopt new features or align with evolving standards. Developers are rapidly adopting AI-powered coding assistants to help with these evolving demands. In this post, we focus on Amazon Q Developer as an example, but the guidance applies broadly to any coding assistant. Amazon Q Developer is an AI-powered assistant that helps developers with code generation, problem-solving, and development tasks within the Amazon Web Services (AWS) ecosystem. Amazon Q Developer command line interface (CLI) allows developers to convert infrastructure definitions between popular IaC frameworks. This post demonstrates how to use Amazon Q CLI to translate a serverless project from a source IaC such as Serverless Framework version 3 to an IaC framework of choice such as the AWS Serverless Application Model (AWS SAM). To make demonstration more accessible, we have chosen a low-complexity project. However, Amazon Q CLI supports bidirectional translation across multiple IaC formats. We walk through how to migrate a reference architecture to show how the process works, as shown in the following figure.

Figure 1. Architecture diagram of example AWS solution to translate

Figure 1. Architecture diagram of example AWS solution to translate

This sample project orchestrates the deployment of a REST API using Amazon API Gateway, acting as an Amazon Simple Storage Service (Amazon S3) proxy for write operations. It includes API-Key setup, basic request validator, AWS Lambda invocation on Amazon S3 events, and enables Amazon CloudWatch Logs and AWS X-Ray tracing for API Gateway and Lambda using the Powertools for Lambda developer toolkit.

Solution overview

Amazon Q Developer is trained on AWS best practices and provides an AI-powered experience through its CLI. It automates IaC translation by reducing manual effort, minimizing errors, and preserving the original intent across frameworks. The translation process follows four steps: assess, translate, test and refine, and deploy. The following figure shows this workflow.

Figure 2. Logical flow for assessment, translation, testing, and deployment

Figure 2. Logical flow for assessment, translation, testing, and deployment

  1. Assess: Analyze existing Serverless Framework projects for compatibility and readiness.
  2. Translate: Convert Serverless Framework configuration into AWS SAM templates using Amazon Q Developer CLI.
  3. Test and refine: Validate and improve translated templates to make sure of functional accuracy and best practices.
  4. Deploy: Package and deploy the finalized AWS SAM templates to AWS environments.

Prerequisites and considerations

The following prerequisites and considerations are necessary to complete this solution.

Define custom rules to guide automation with Amazon Q Developer

Amazon Q Developer uses a rule-based model to automate tasks that is guided by user-defined rules. These rules encode your team’s standards to make sure that the automation is consistent and repeatable. You can create a library of custom rules to enforce best practices when using Amazon Q in your integrated development environment (IDE) or through the CLI. To help you get started, we’ve included a sample rules file that provides a baseline configuration. This file defines the structure of the output, sequence of the automation steps, and best practices to follow during each phase of the project. You can customize these rules to align with your organization’s architectural guidelines, security policies, or compliance needs.

Understand and categorize project complexity

Serverless projects differ in scale and structure, which directly impacts how you assess them. Smaller projects with minimal configuration and a few functions typically present fewer challenges. Larger, more complex projects can include dozens of Lambda functions, shared layers, and integrations across services such as Amazon Simple Queue Service (Amazon SQS), Amazon DynamoDB, or Amazon EventBridge. Start by categorizing the project as low, medium, or high complexity based on factors such as the number of functions, the diversity of event sources, and the presence of shared configurations. Use this categorization to prioritize and scope your assessment efforts. For complex workloads, assess individual components separately to reduce the surface area for troubleshooting and remediation.

Handle framework-specific tooling and plugins

Plugins or dependencies in different IaC frameworks extend core functionality or introduce custom behaviors. AWS SAM supports similar capabilities but in a different way. For example, you may be able to use AWS SAM, but for capabilities not found in AWS SAM, you can use AWS CloudFormation macros or Lambda-backed custom resources. During assessment, identify all active plugins and document their purpose and integration points. Evaluate whether each plugin’s functionality can be replicated using native AWS services or custom resources in AWS SAM. For common patterns—such as packaging optimizations, function warmers, or custom deploy hooks—consider using the CloudFormation macros and custom resources. When plugin functionality cannot be translated directly, annotate it in your assessment report for manual intervention. Clearly mapping each plugin’s role helps maintain parity and reduces surprises during deployment in the new environment.

With all of this you are ready to start the conversion.

Assess with Amazon Q Developer

The animated diagrams included in this post offer step-by-step visuals to explain the Amazon Q behavior throughout the workflow. Remember that you have already set rules for Amazon Q for each phase. Now your prompt to Amazon Q is clear. At this point Amazon Q has enough context to get you crisper and deterministic result. Use the following prompt to start the assessment:

Prompt

Evaluate the readiness of the Serverless Framework v3 project for 
translation to AWS SAM using the provided assessment rules.
Figure 3. Assessment step using Amazon Q Developer

Figure 3. Assessment step using Amazon Q Developer

After the assessment, Amazon Q Developer generates translation recommendations based on AWS best practices. It produces an evaluation_summary.md file with detailed insights, mapping guidance, and technical considerations for converting components to AWS SAM resources. The report serves as the foundation for the next step: automated translation into AWS SAM resources.

Translate using Amazon Q Developer

After completing the assessment, begin the translation using the baseline rules defined in .amazonq/rules/translation_rules.md. These rules guide the conversion and make sure of consistency with the assessment outputs. Amazon Q Developer CLI uses these rules to parse the serverless.yml file, scaffold a new project structure, and generate a complete AWS SAM template. During translation, Amazon Q Developer performs the following actions:

  • Converts each Lambda function into an AWS::Serverless::Function, preserving runtime, handler, memory, timeout, and environment settings.
  • Translates event sources such as HTTP APIs and Amazon SQS into SAM event definitions.
  • Maps AWS Identity and Access Management (IAM) policies and permissions into CloudFormation-compatible resources.
  • Removes development-only settings such as the serverless-offline plugin.

Serverless Framework v3 often uses CloudFormation orchestration and custom resources to deliver certain capabilities. For example, it may use custom resources to provision S3 bucket notifications. Amazon Q detects these patterns during assessment and translates them into explicit, well-structured AWS SAM resources. This makes sure of functional parity in the target IaC.Use the following prompt to begin the translation:

Prompt

Apply the translation rules to migrate this Serverless Framework 
v3 project into an AWS SAM project while maintaining all 
original infrastructure behavior.
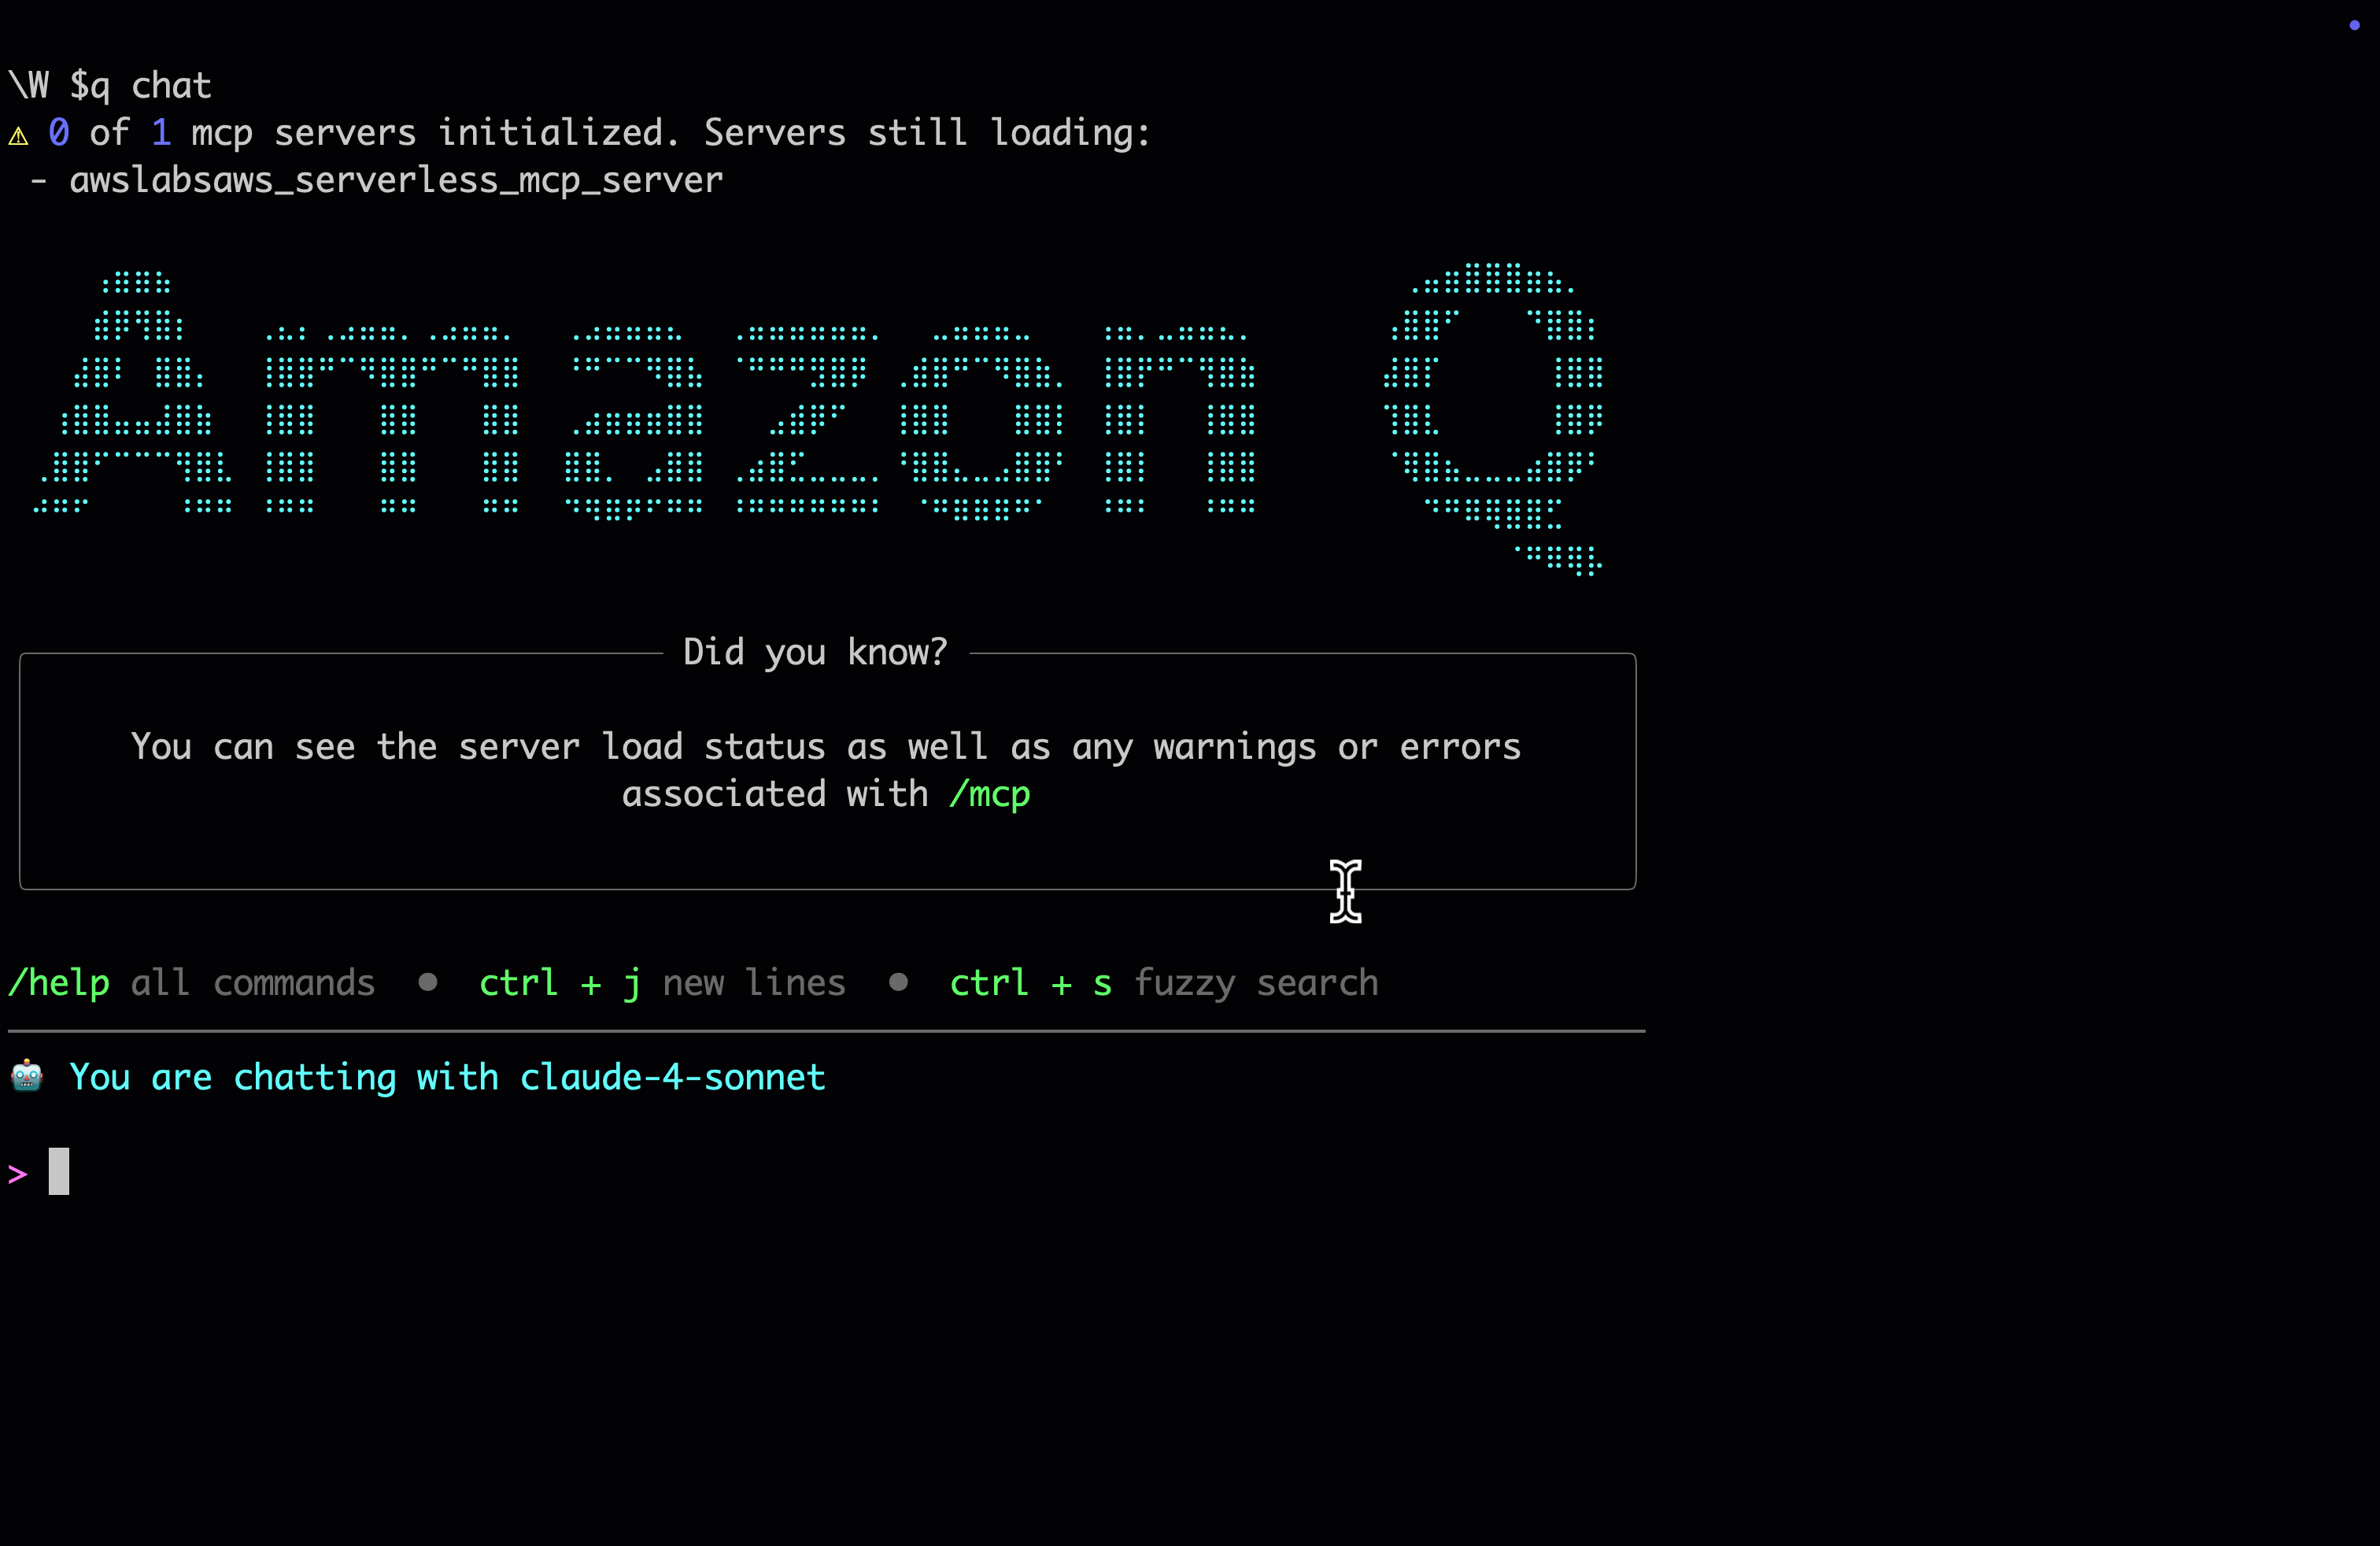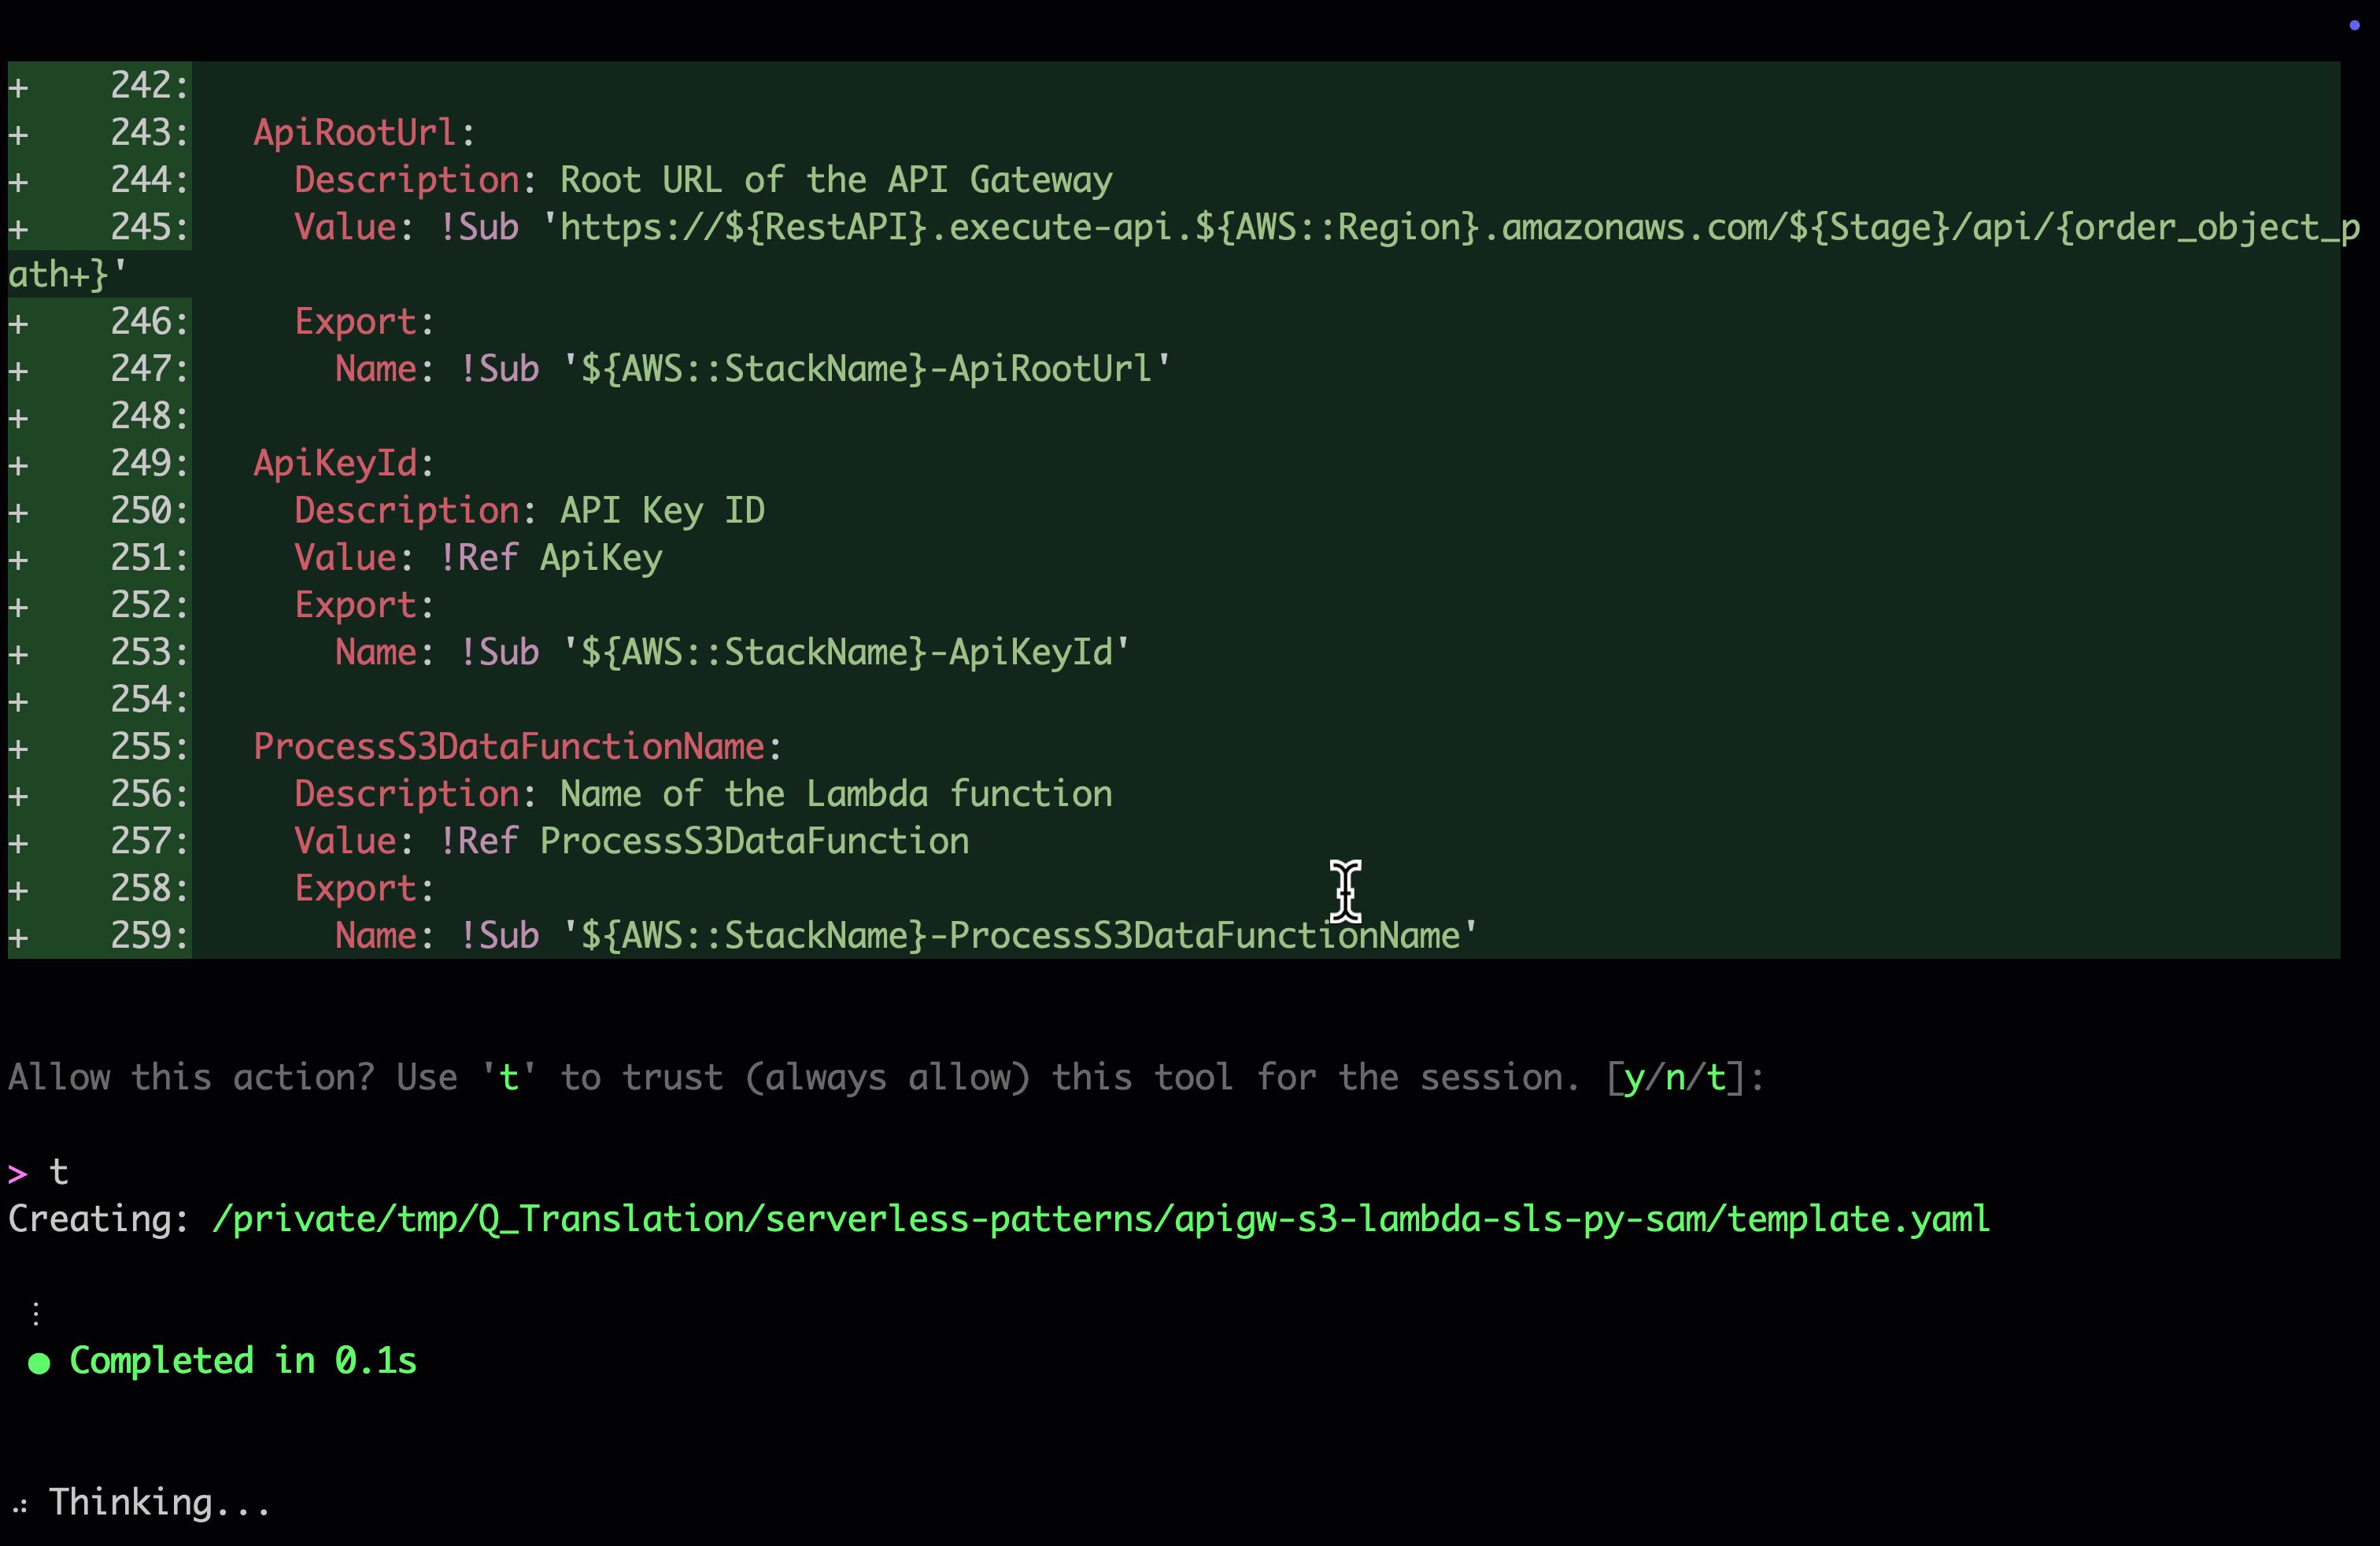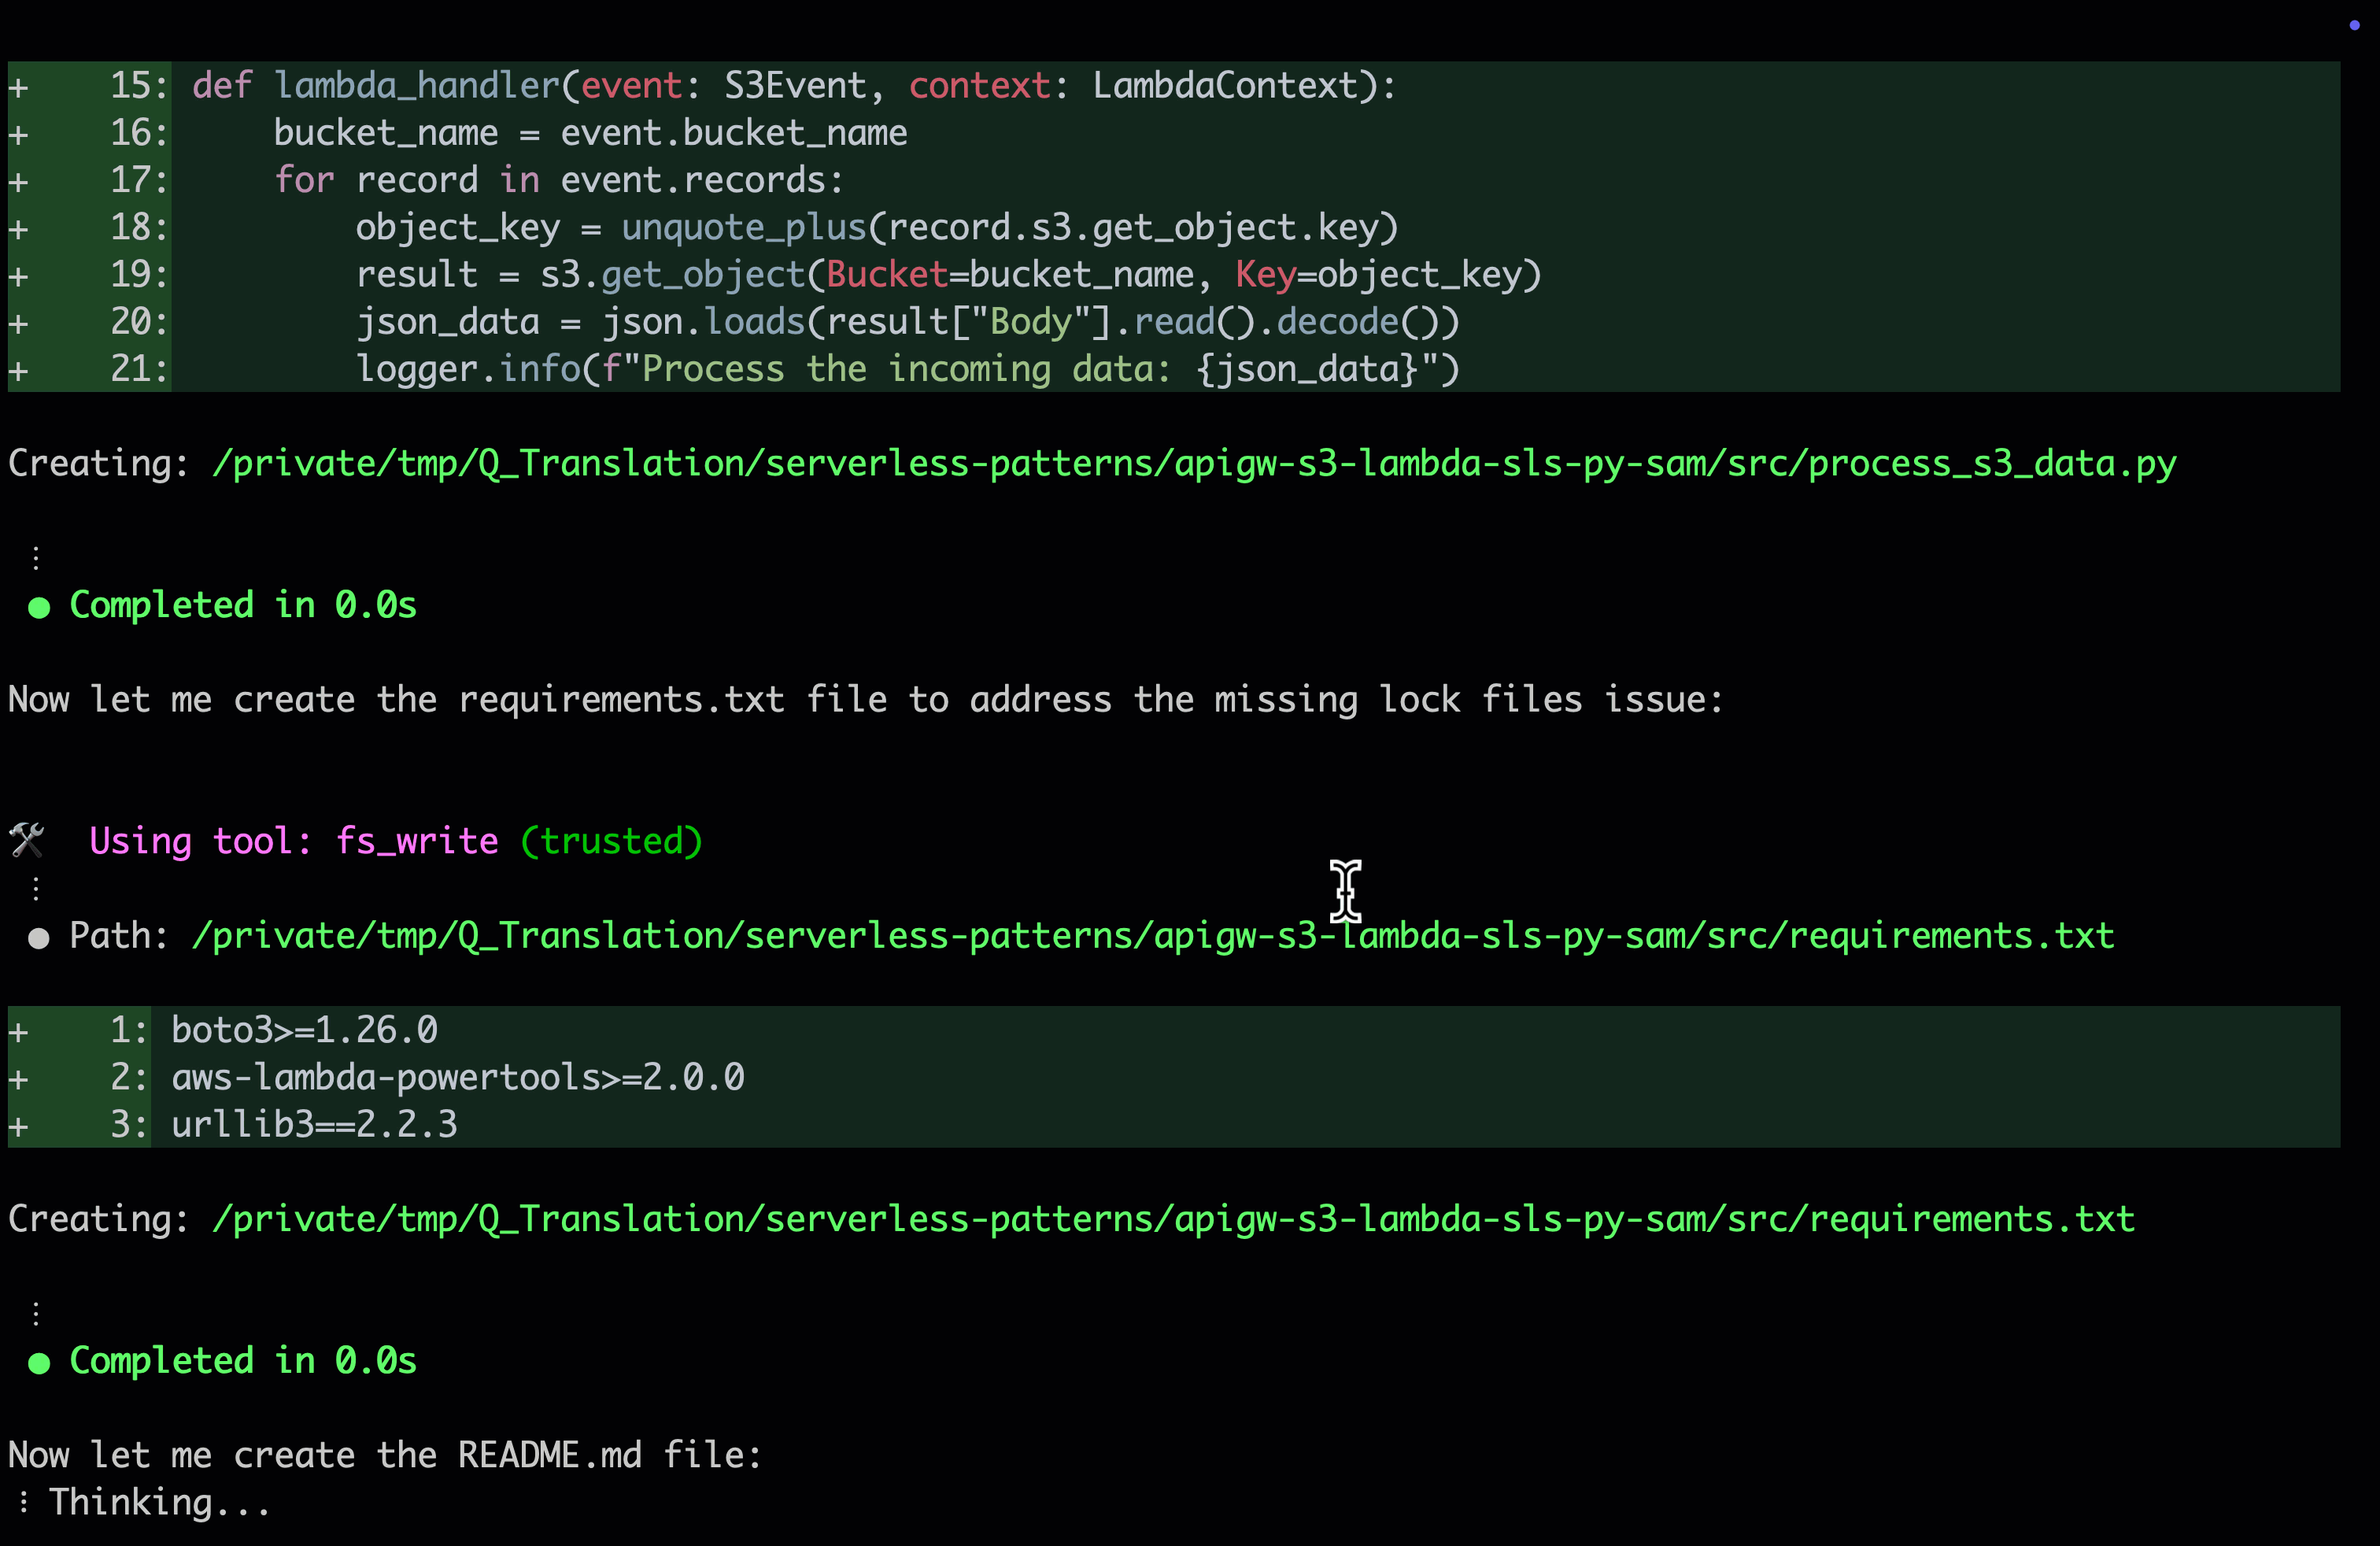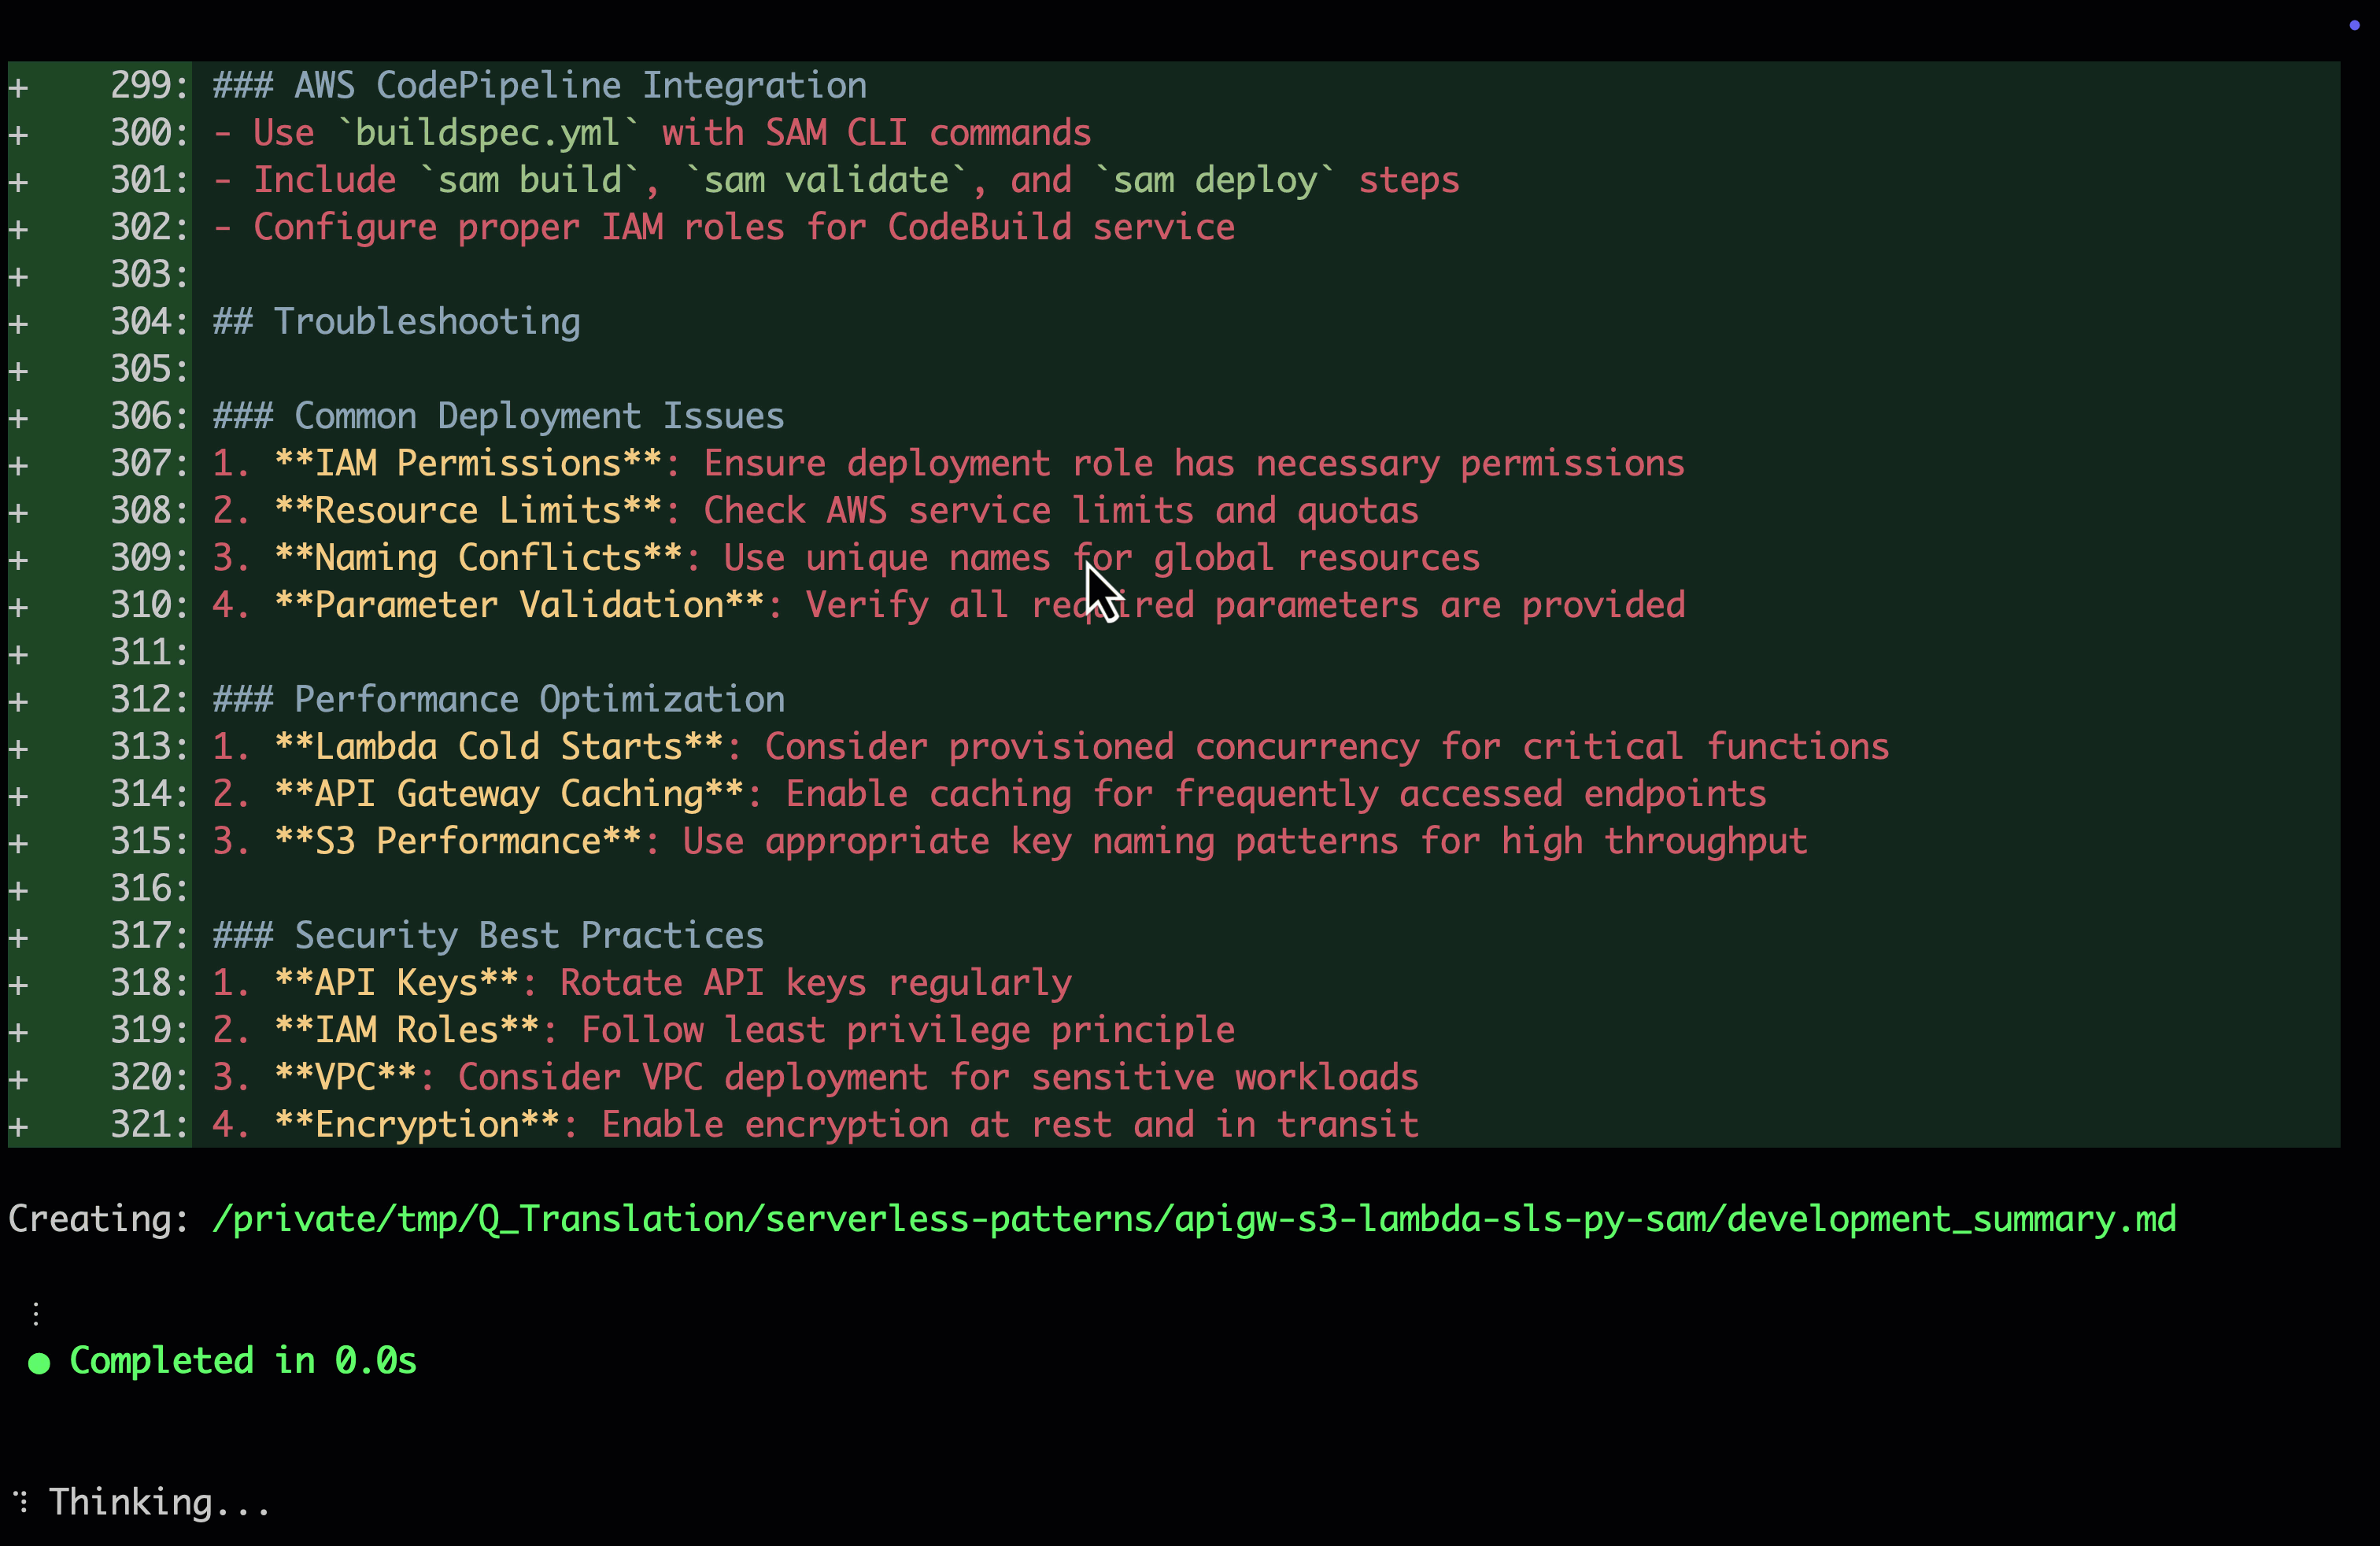
Figure 4. Translation using Amazon Q Developer

Figure 4. Translation using Amazon Q Developer

After translation, Amazon Q Developer produces a complete AWS SAM project with test scripts and documentation. The project supports local testing, automated deployment, consistent resource management, and native integration with AWS tools. You also receive a development_summary.md file with a structured project overview and step-by-step testing instructions.

Amazon Q Developer replaces resources created implicitly by Serverless Framework plugins (such as Serverless Lift or custom resources for handling circular dependencies) with explicit CloudFormation definitions. To support custom or unsupported plugins, define the translation logic in .amazonq/rules/development_rules.md. Specify mappings or flag resources for manual review. This maximizes automation while highlighting exceptions early in the workflow.

Test and refine using Amazon Q Developer

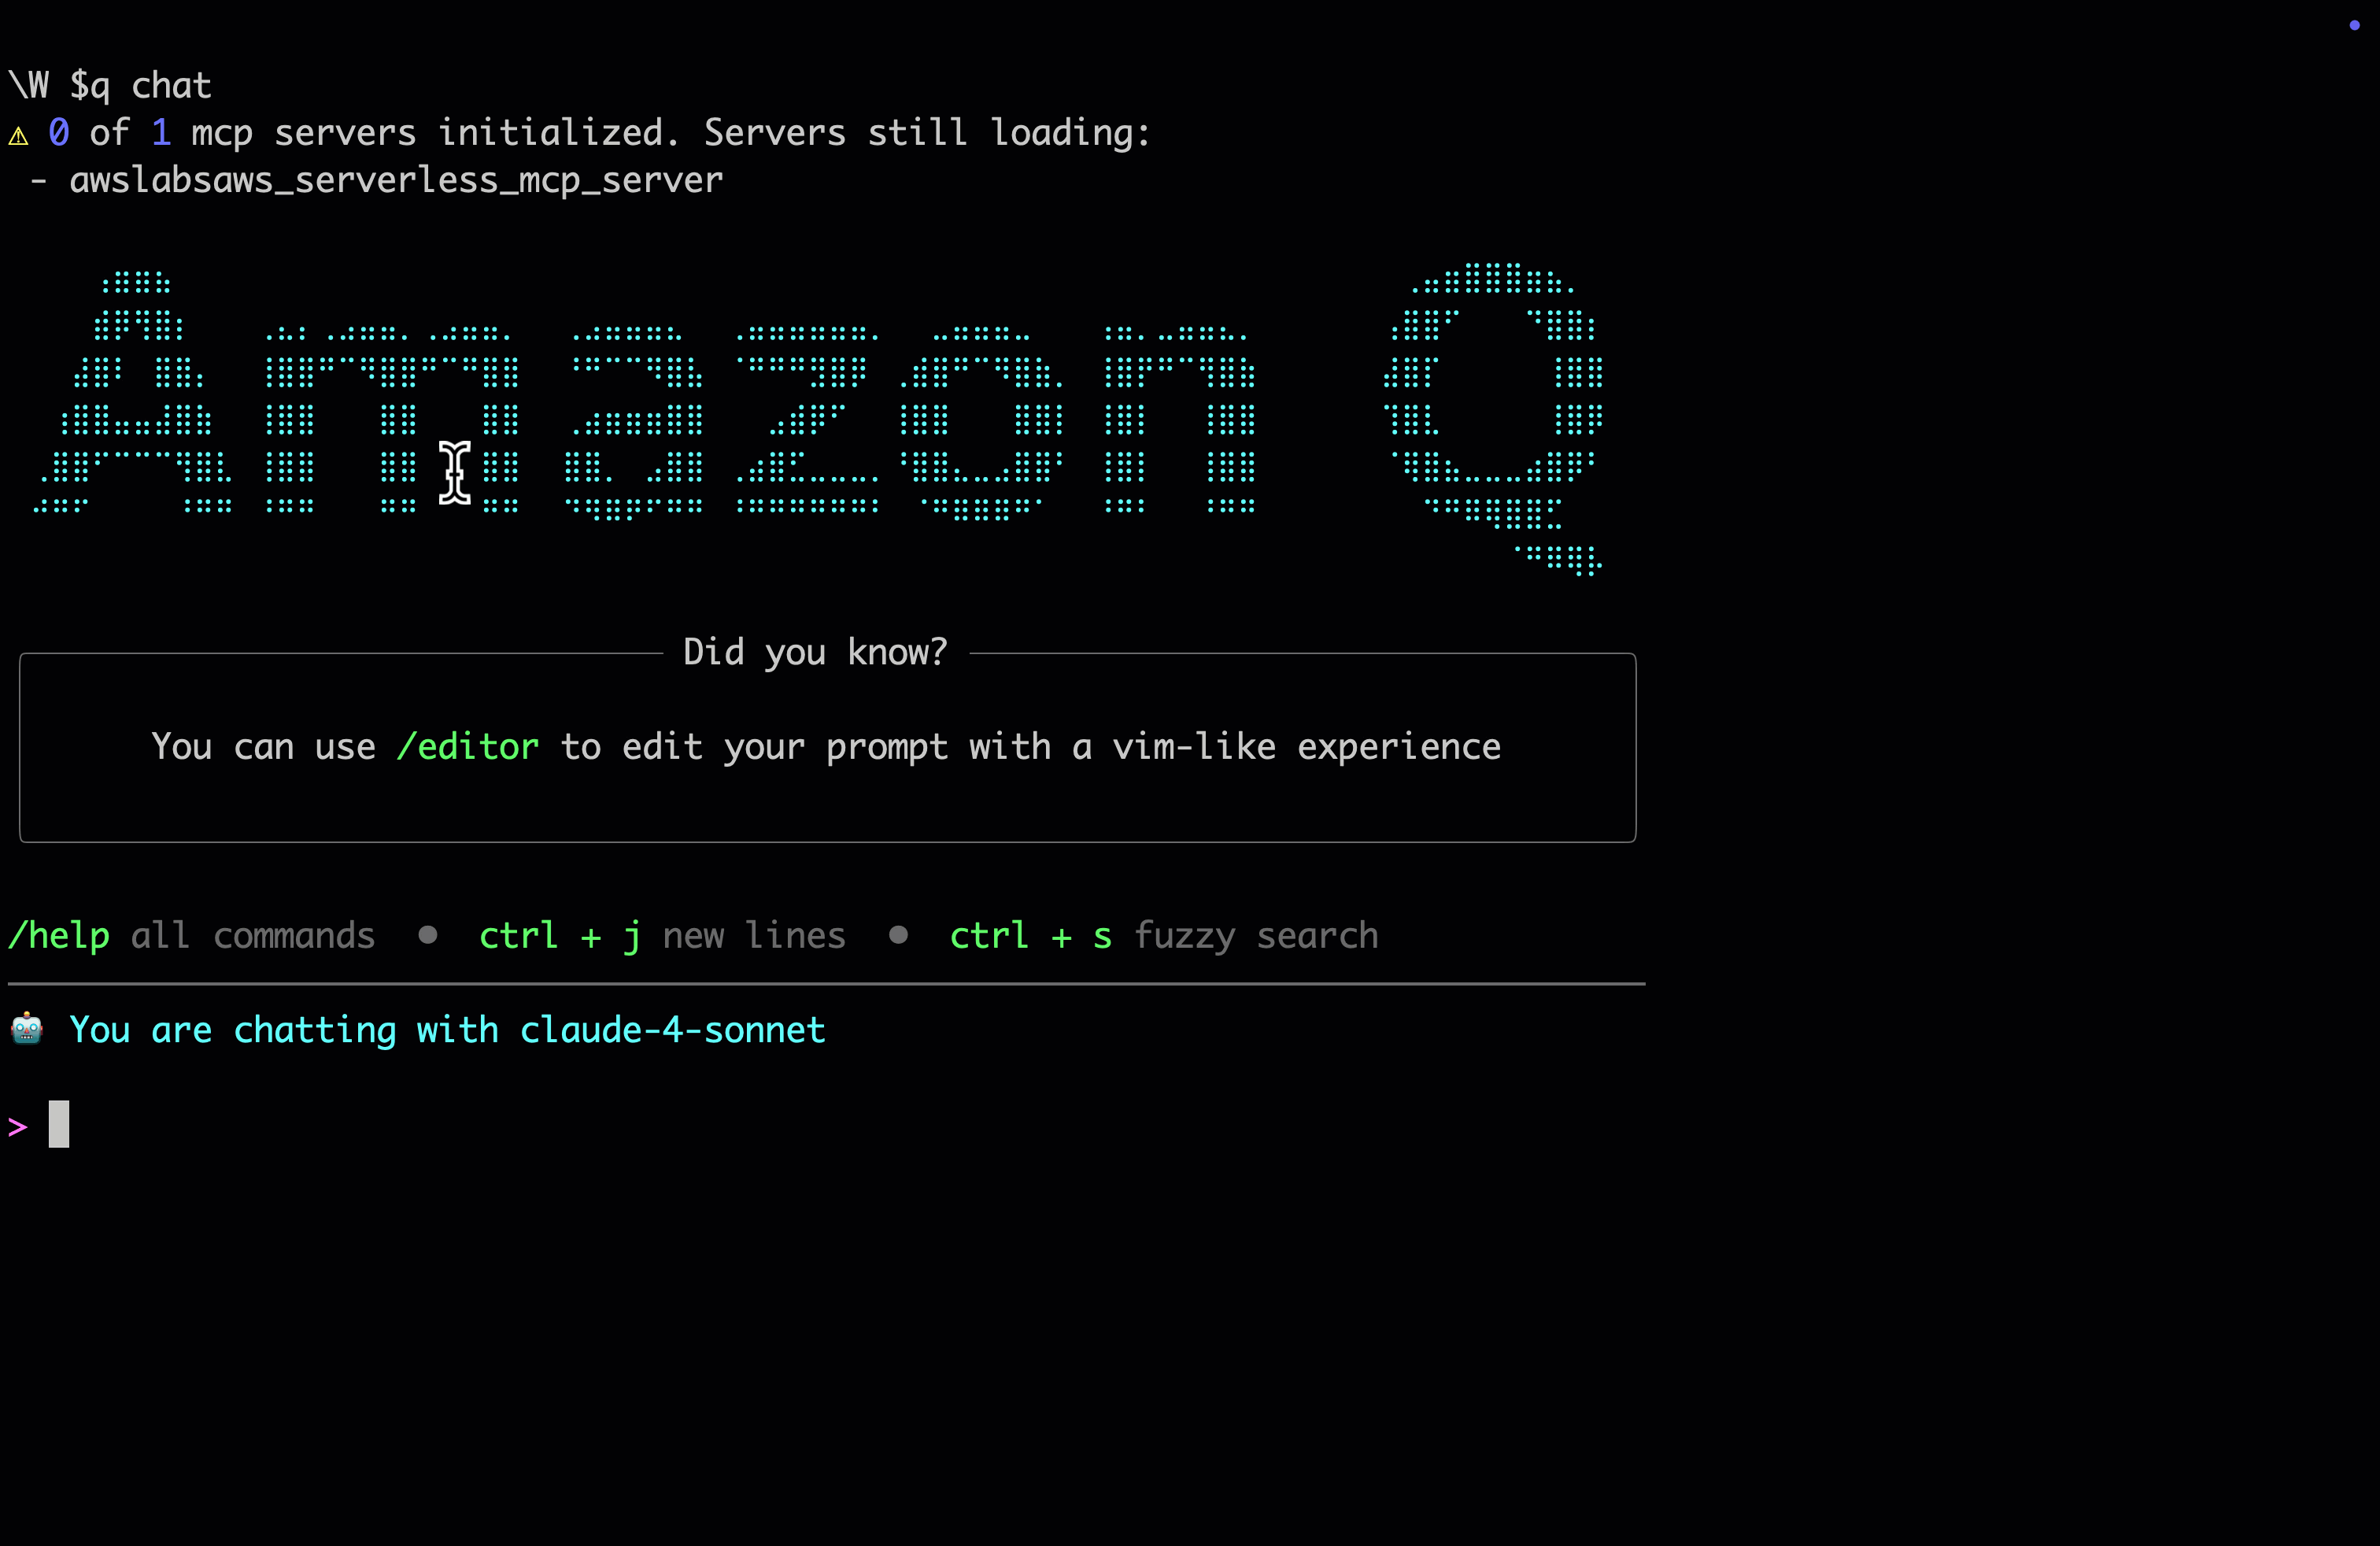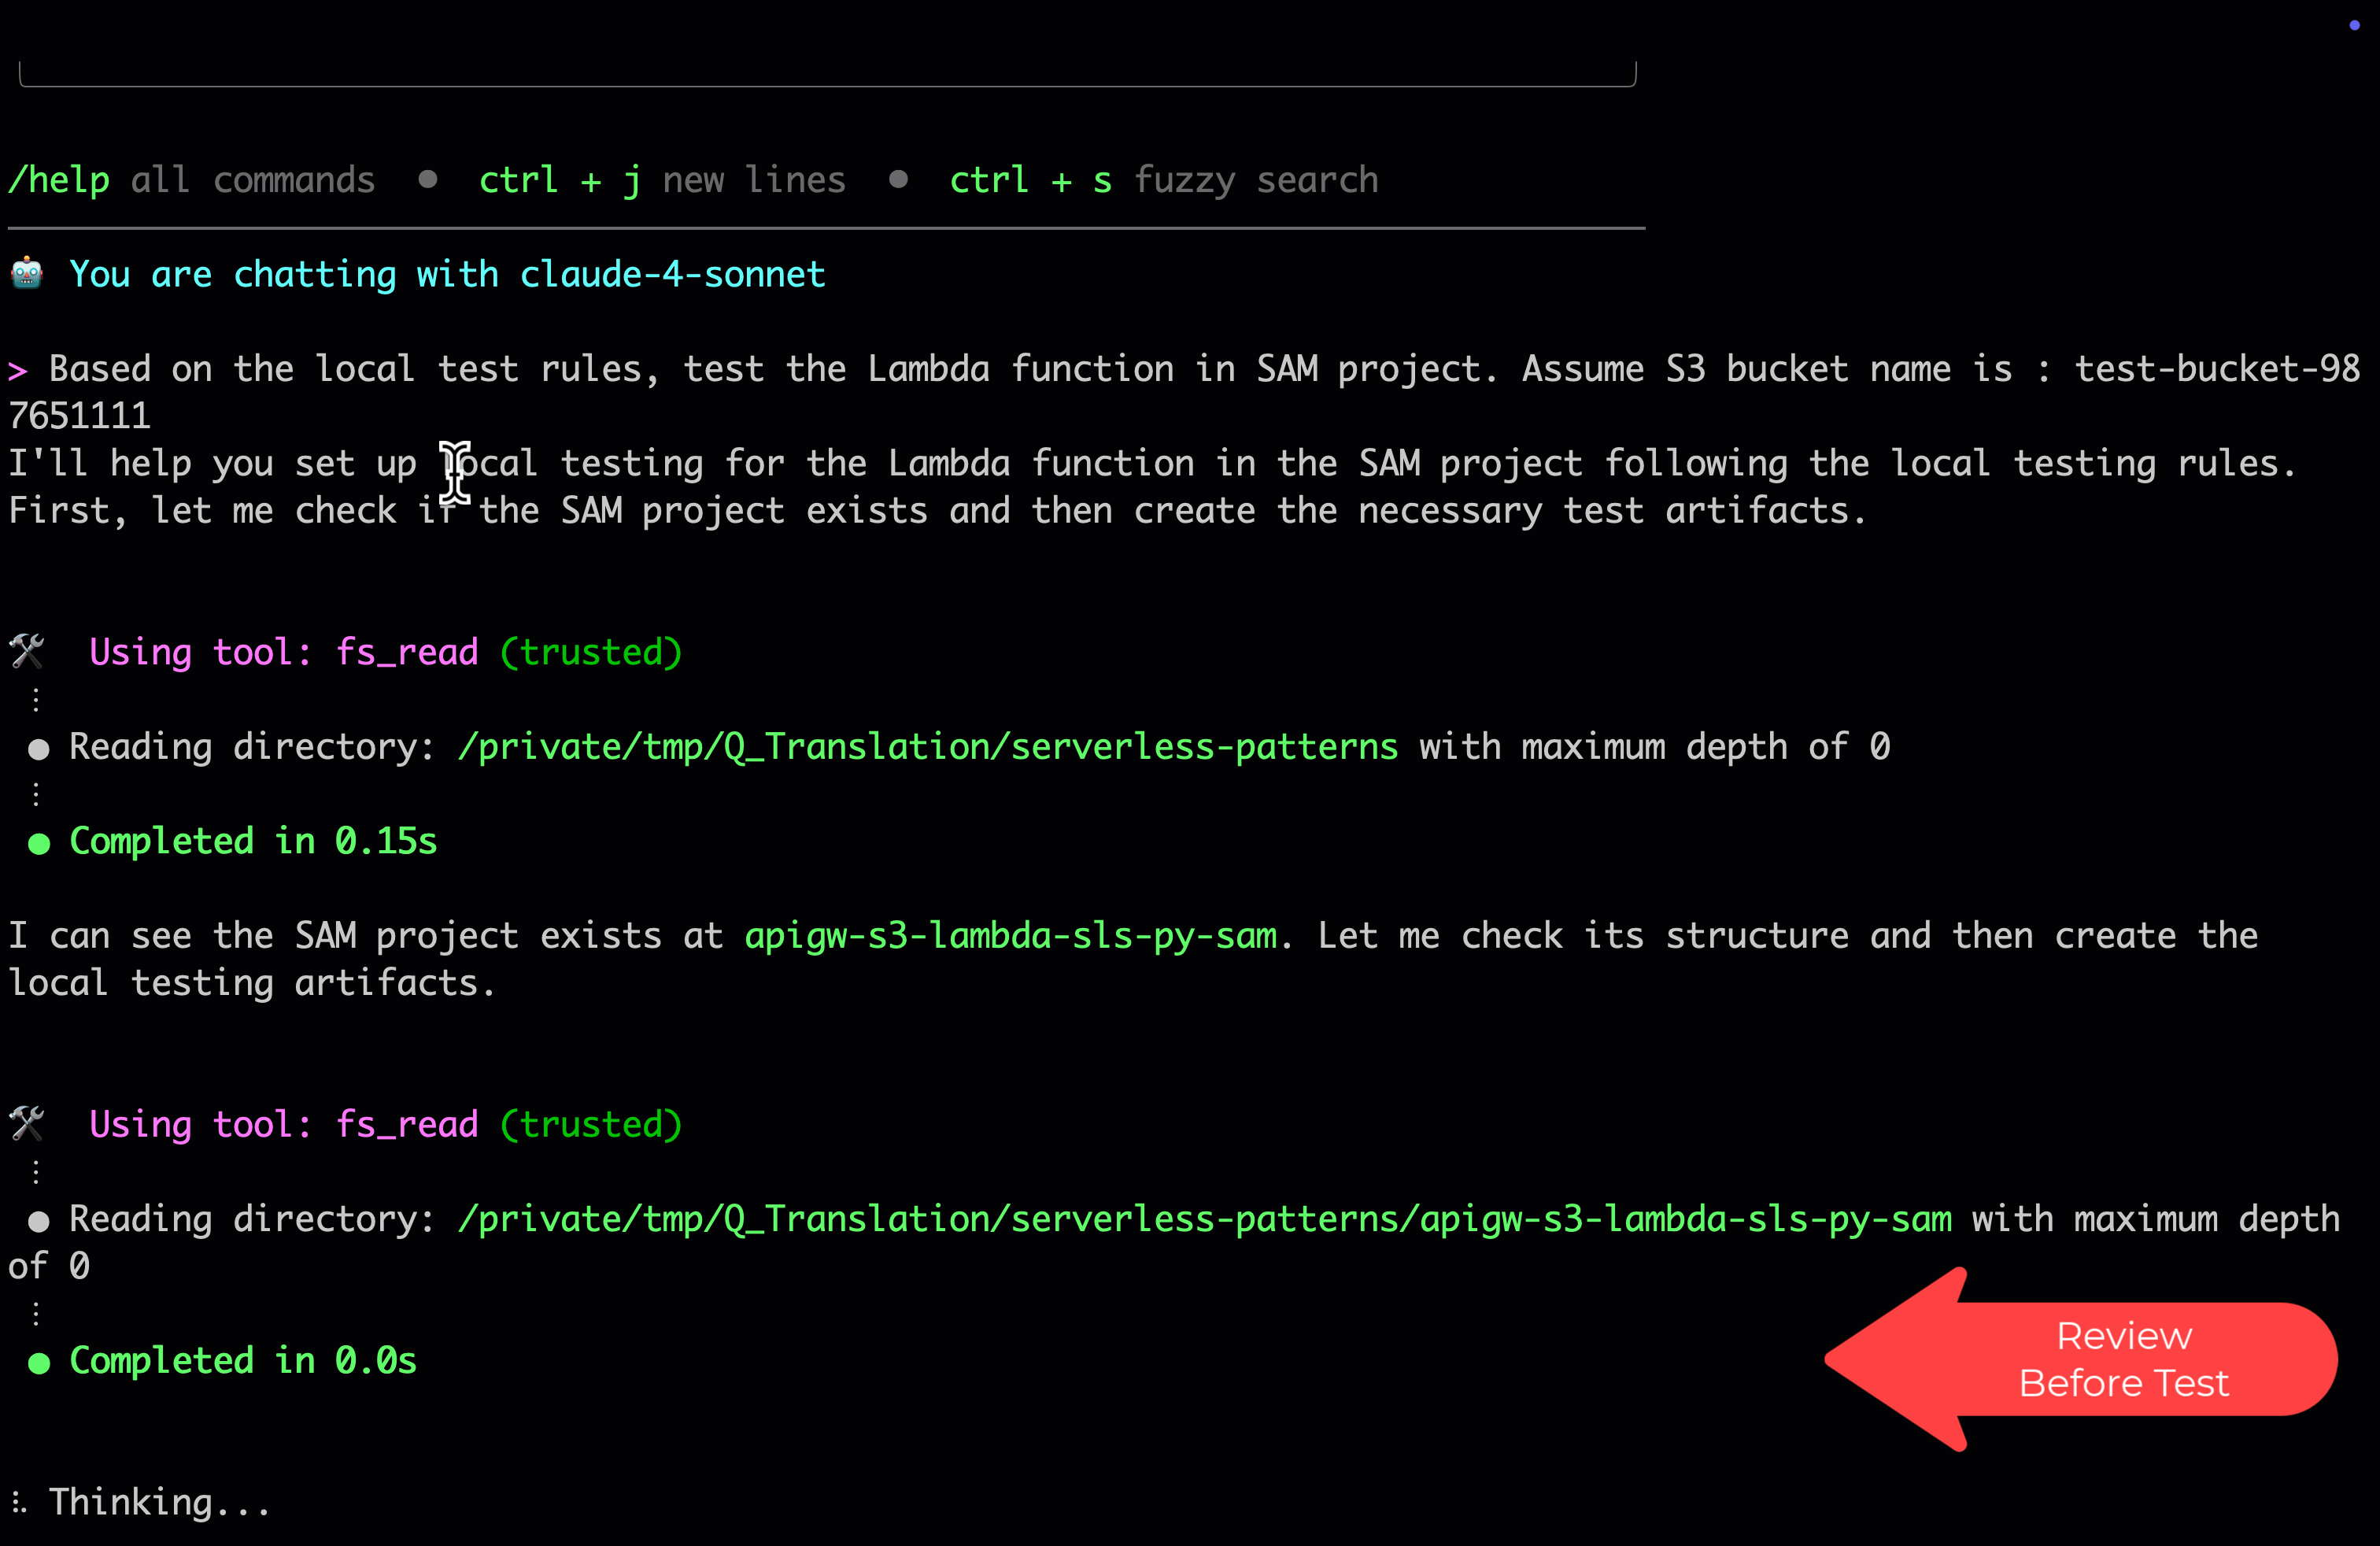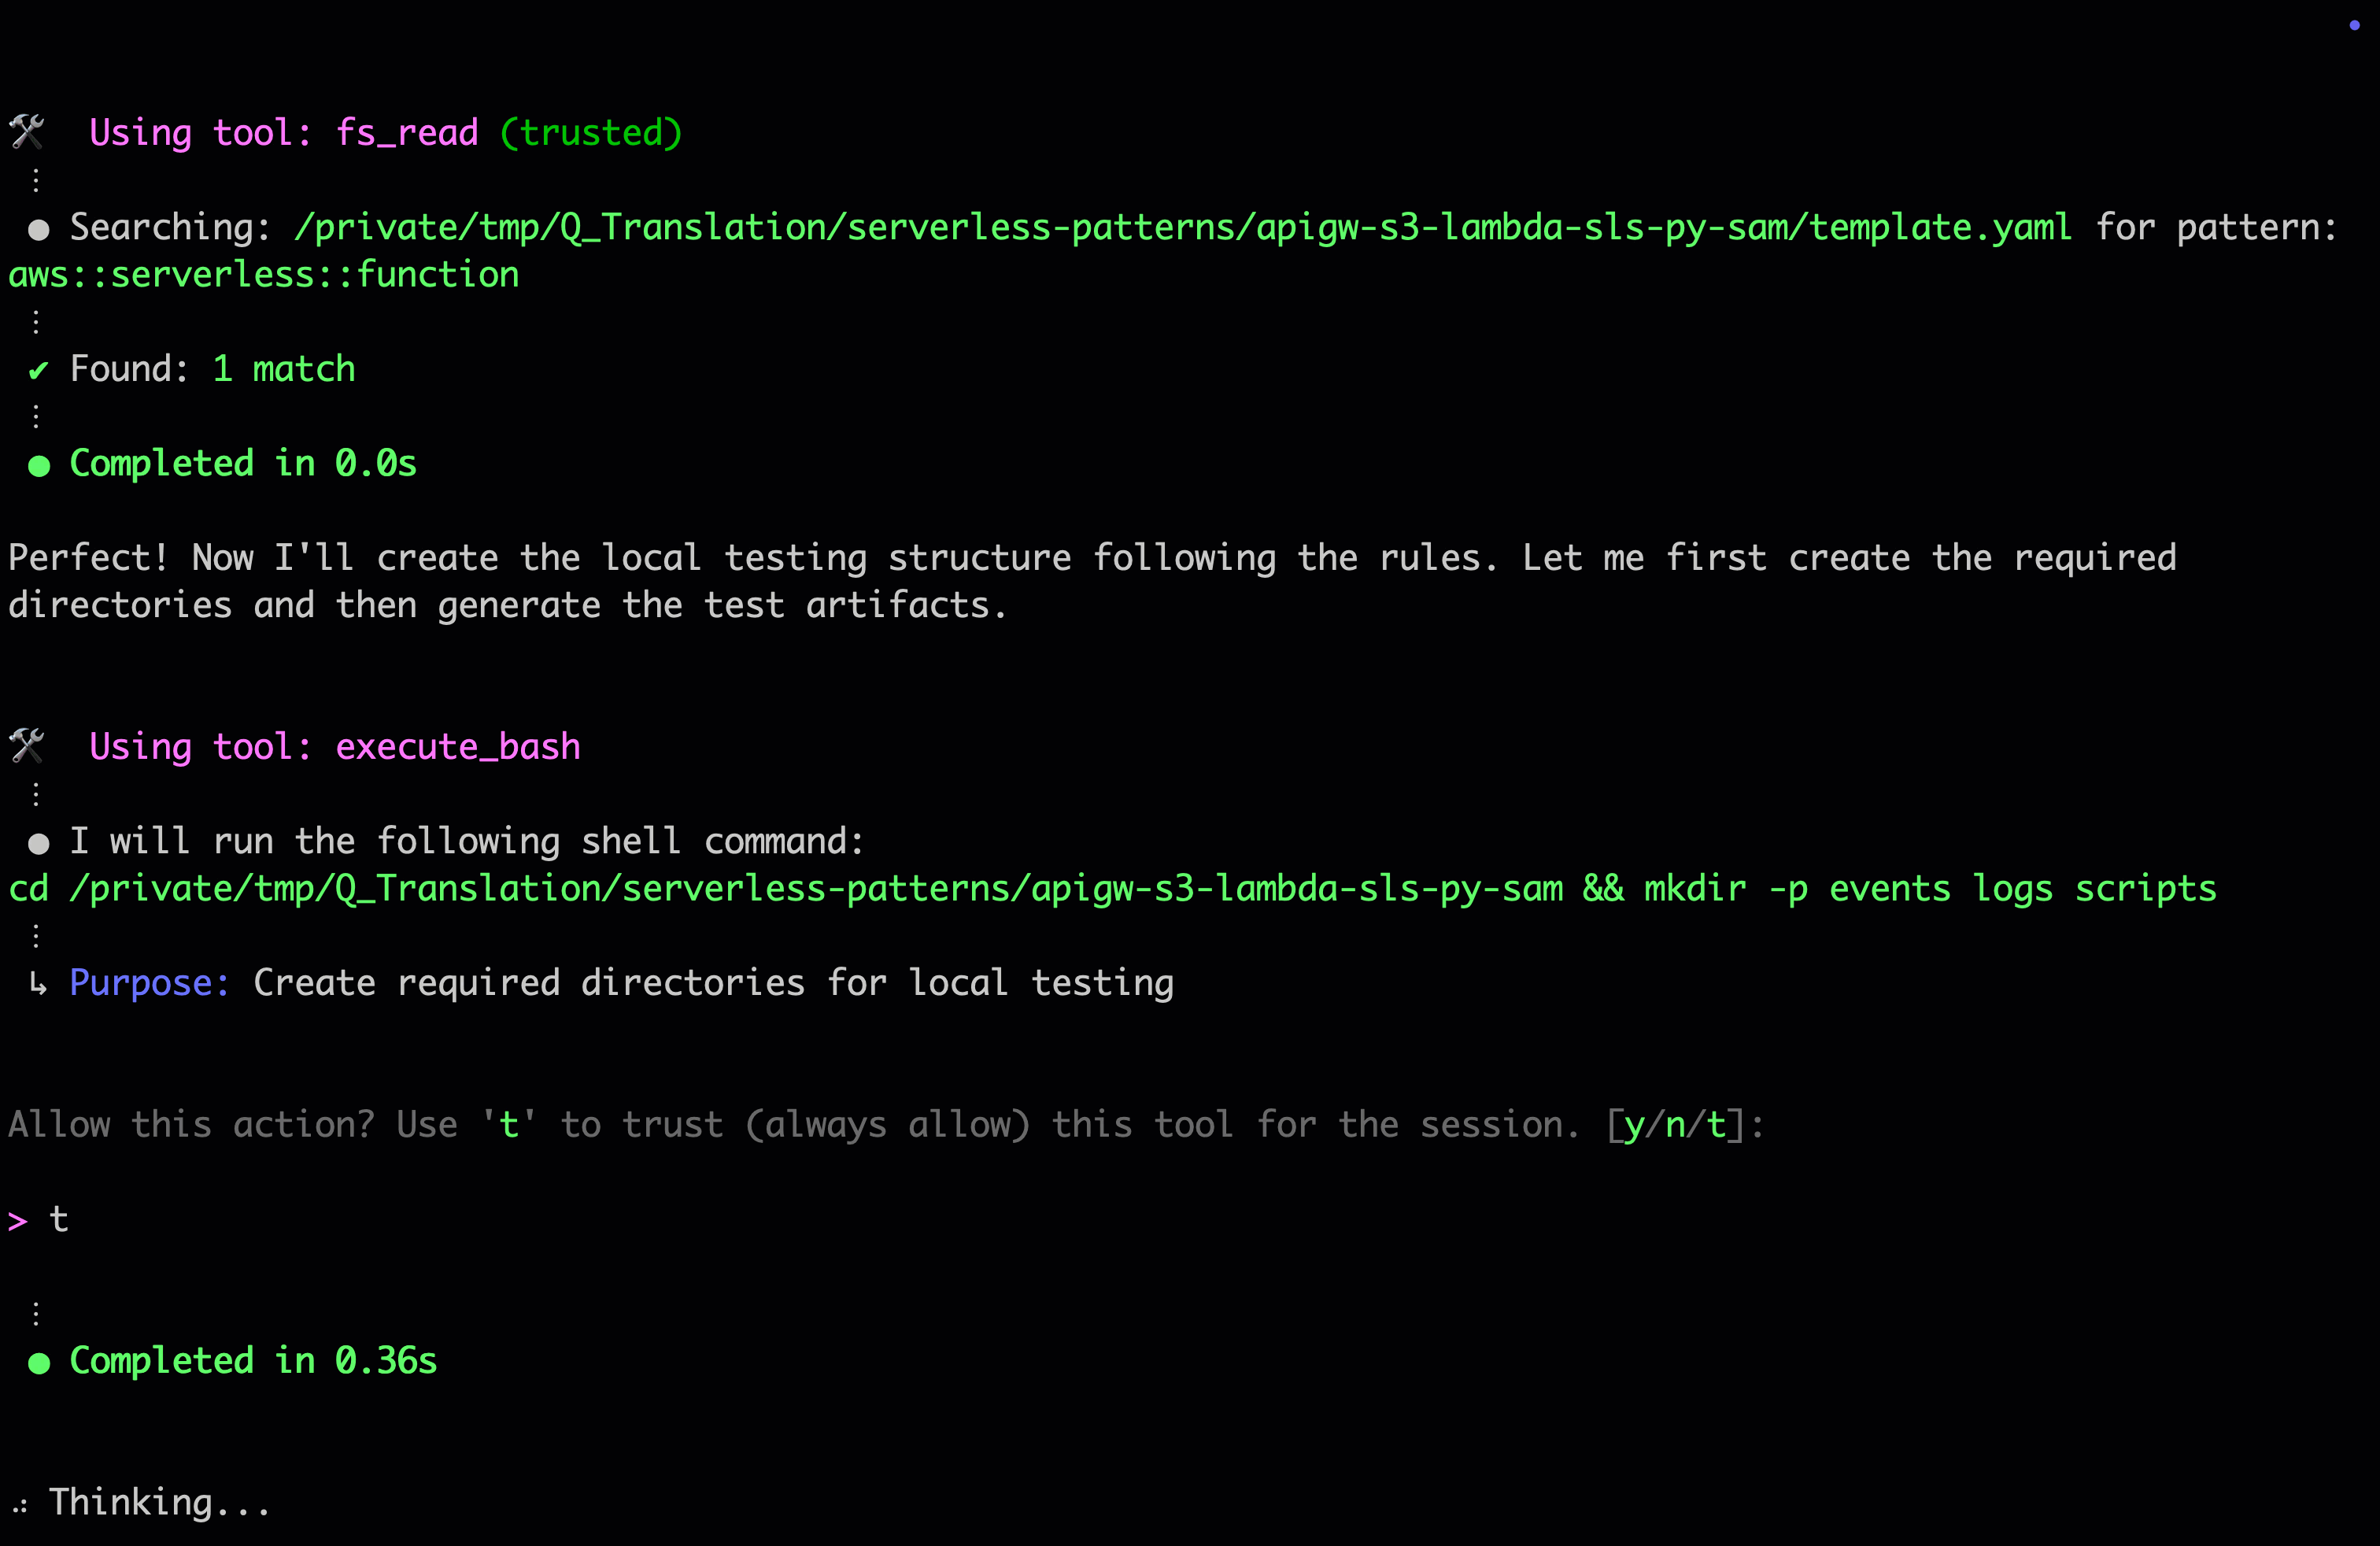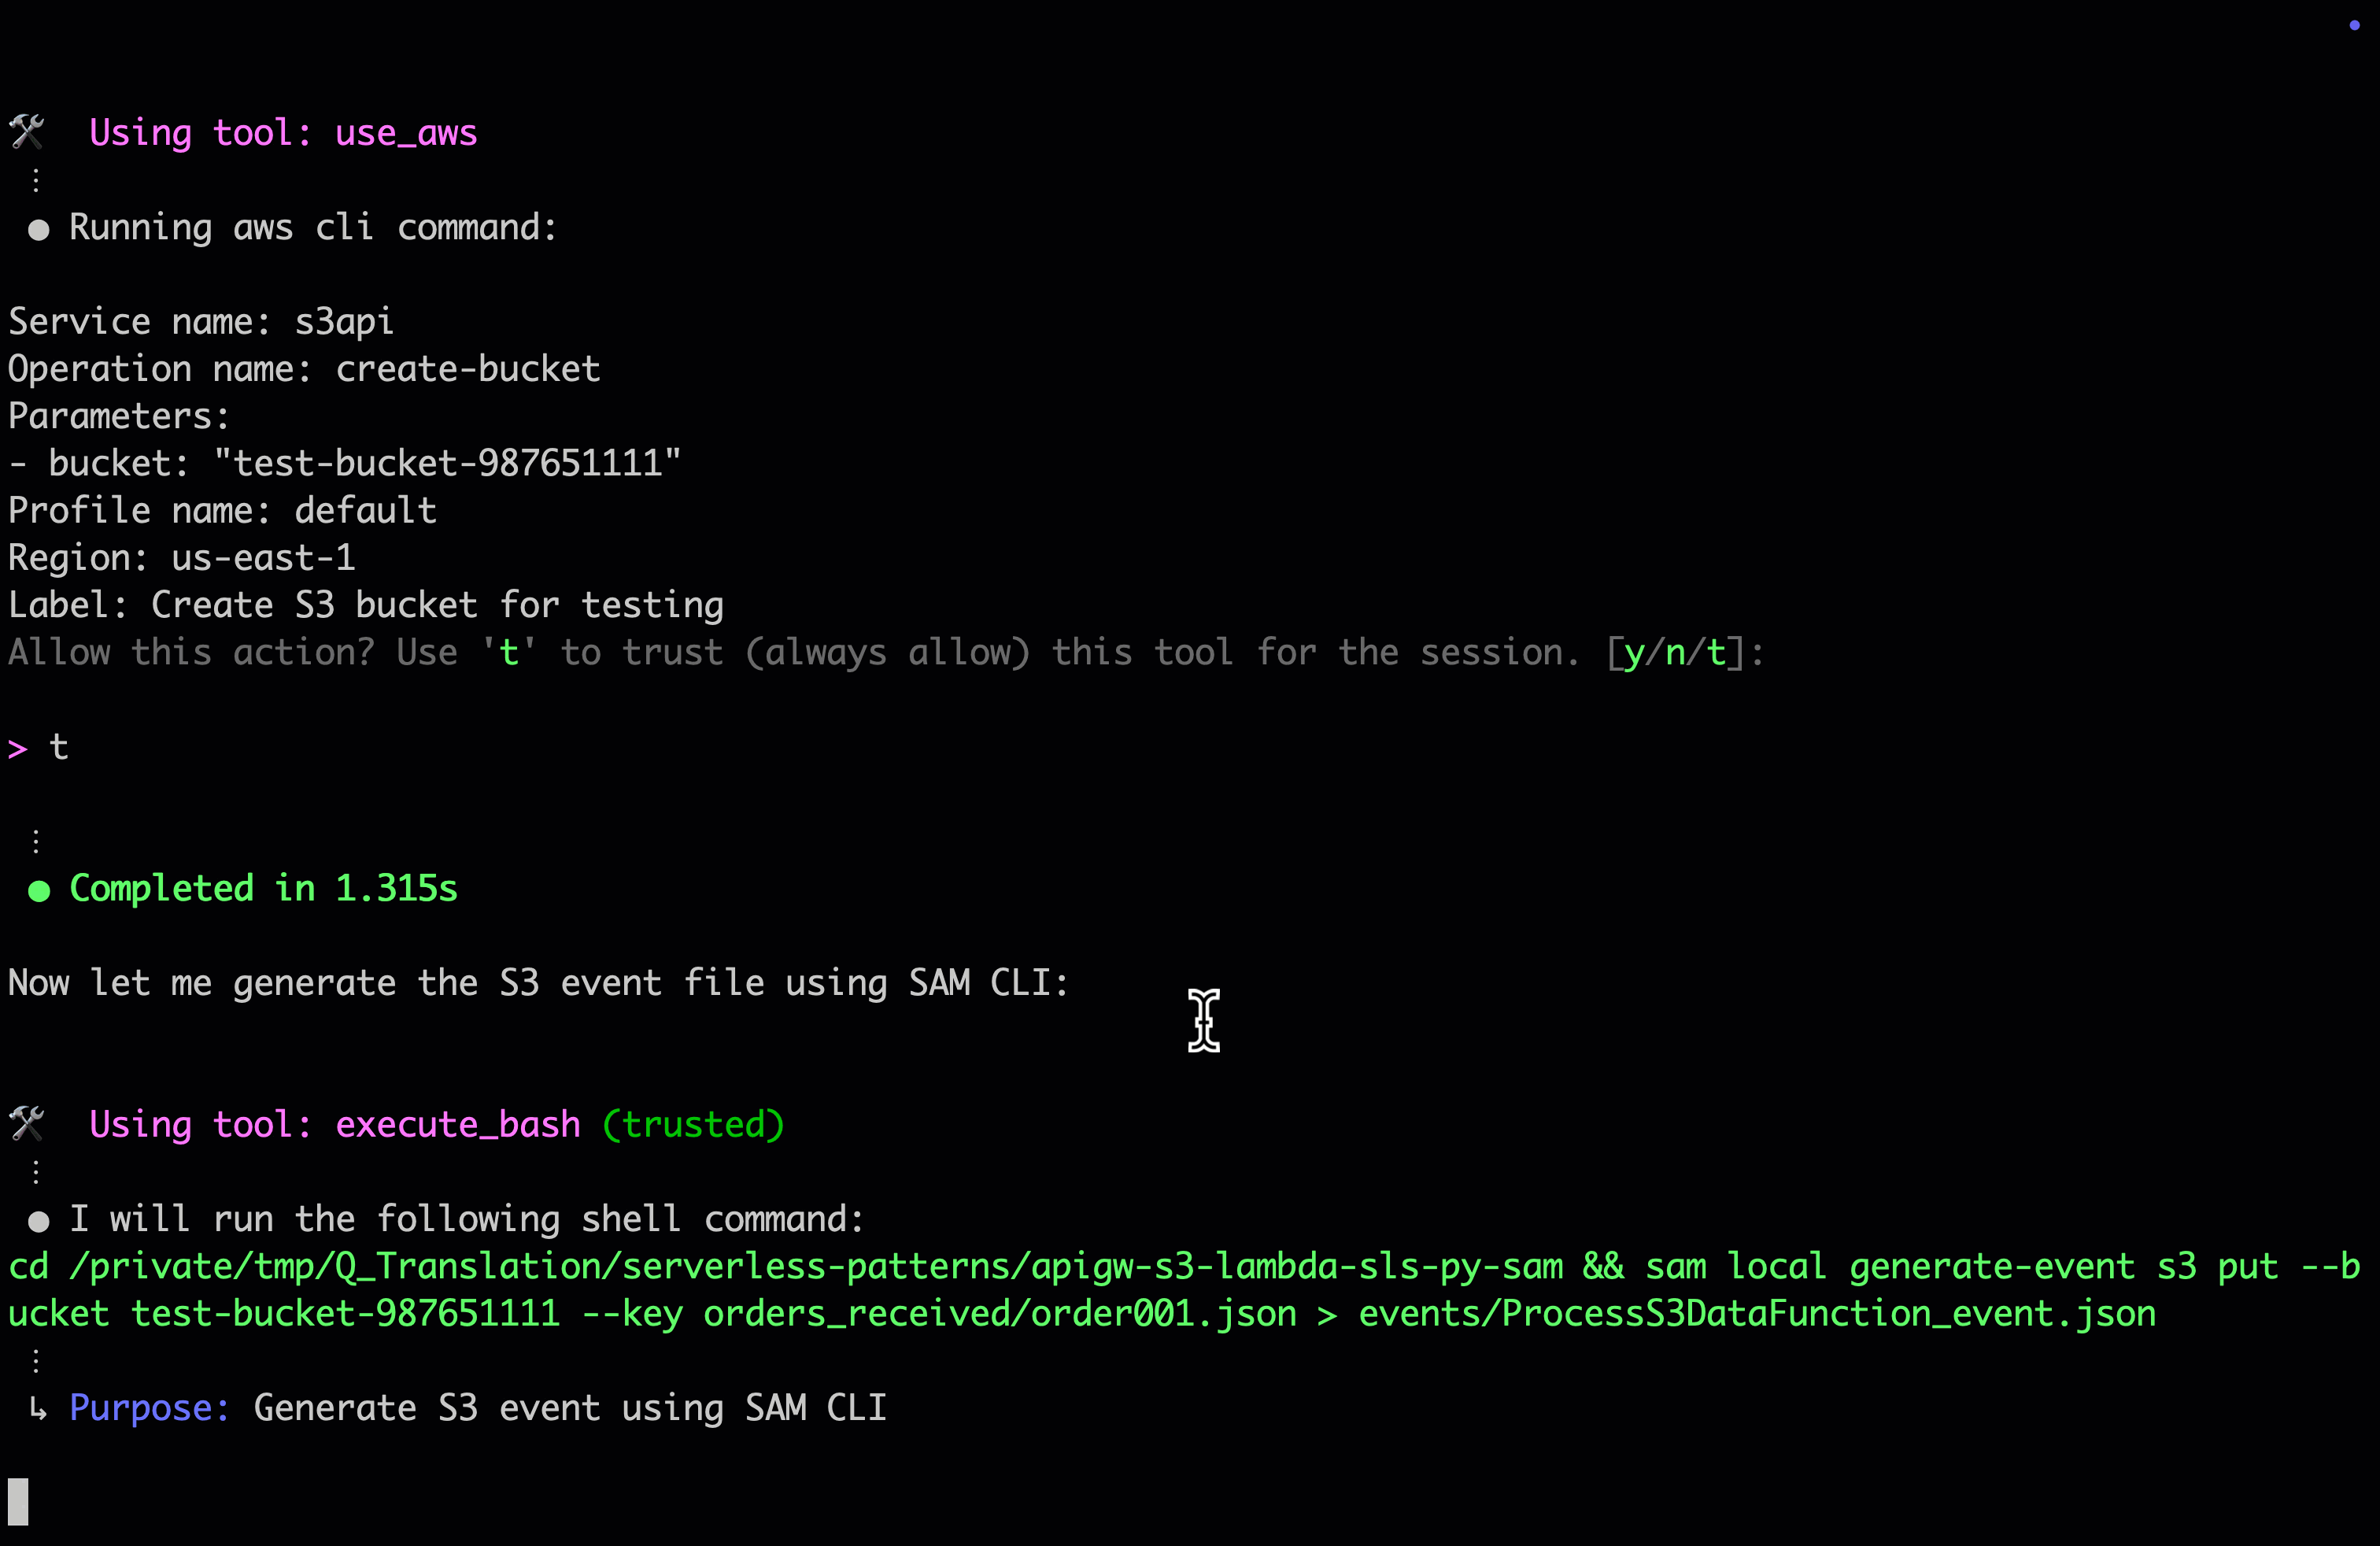
Validate the translated AWS SAM application using the local testing rules defined in .amazonq/rules/local_testing_rules.md. These rules guide high-fidelity simulation and verification.

Amazon Q Developer generates test commands that use the AWS SAM CLI to replicate real-world behavior. It uses sam local invoke to test Lambda functions and sam local start-api to simulate HTTP API calls. This makes sure of the translated application behaves as expected when compared to the original Serverless Framework project.

To simulate Amazon S3 events, provision temporary S3 buckets, and instruct Amazon Q Developer to reference them during testing, it enables full end-to-end validation by combining real Amazon S3 interactions with a local function execution.Use the following prompt to begin testing:

Based on the local test rules, test the Lambda function in 
SAM project. Assume S3 bucket name is : <BUCKET_NAME>
Figure 5. Testing and refinement step using Amazon Q Developer

Figure 5. Testing and refinement step using Amazon Q Developer

Use AWS SAM Accelerate with sam sync to run cloud-based integration tests in a lower environment after completing local validation. This complements early testing and helps catch runtime issues before deployment. Combining Amazon Q Developer automation with AWS SAM CLI allows you to speed up feedback cycles and make sure of functional accuracy in the cloud environment.

Deploy

The translated and tested AWS SAM application is ready, thus the final step is deployment. Using AWS SAM CLI, package and deploy the application to an AWS environment where it becomes fully operational. Begin by running the following:sam build

This command prepares the application for deployment by packaging the Lambda function code, resolving dependencies, and creating build artifacts in the .aws-sam directory.Next, deploy the application using the following:

sam deploy --guided

The --guided flag walks you through the initial configuration, such as stack name, AWS Region, and necessary capabilities such as IAM role creation. When it’s complete, CloudFormation provisions all resources defined in the template.yaml, such as Lambda functions, API Gateway endpoints, SQS queues, and IAM policies. Here is how the output looks from the deployment:

Key                 ApiGKeyId
Description         API Gateway Key ID
Value               j5u41XXXXXX

Key                 S3BucketName
Description         Name of the S3 bucket
Value               bb245-sfp-XXXXXXXXXX

Key                 ApiRootUrl
Description         Root URL of the API Gateway
Value               https://XXXXXXXX.execute-api.us-east-1.amazonaws.com/dev/api/{order_object_path+}

Key                 ProcessS3DataFunction
Description         ProcessS3Data Lambda Function ARN
Value               arn:aws:lambda:us-east-1:0123456789012:function:q-generated-stack-ProcessS3DataFunction-
jvXXXXXXXMAT

AWS SAM emphasizes explicit definitions such as resource names and parameters. Therefore, using the AWS SAM guided deployment here helps by presenting change set reviews to verify these changes.Now that you’ve translated and tested your AWS SAM application, verify its parity with the original Serverless Framework stack. Compare CloudFormation outputs—API Gateway endpoints, S3 bucket names, Lambda Amazon Resource Names (ARNs), and queue URLs—and automate integration or A/B tests to confirm functional equivalence. Then, deploy the AWS SAM version using a canary release, monitor performance and user metrics, and shift traffic gradually to minimize risk.

Cleaning up

If you no longer need the AWS resources that you created by running this example, then you can remove them by deleting the CloudFormation stack that you deployed.

To delete the CloudFormation stack, use the sam delete command:

sam delete --stack-name apigw-s3-lambda-sam-stack

Conclusion

In this post you’ve learned how Amazon Q Developer CLI can streamline the translation of IaC by using an example of migrating Serverless Framework to AWS SAM. Using AI-powered conversational interfaces and deep integration with AWS knowledge means that Amazon Q Developer substantially reduces the manual effort and potential errors involved in these translations. Comprehensive assessment, translation, testing, and deployment can be difficult to accelerate, but this can be streamlined with new generative AI tools from AWS.

For more information on Amazon Q, you can check out Amazon Q Developer. For more serverless learning resources, visit Serverless Land. To find more patterns, go directly to the Serverless Patterns Collection.

Modernizing SOAP applications using Amazon API Gateway and AWS Lambda

Post Syndicated from Daniel Abib original https://aws.amazon.com/blogs/compute/modernizing-soap-applications-using-amazon-api-gateway-and-aws-lambda/

This post demonstrates how you can modernize legacy SOAP applications using Amazon API Gateway and AWS Lambda to create bidirectional proxy architectures that enable integration between SOAP and REST systems without disrupting existing business operations.

Many organizations today face the challenge of maintaining critical business systems that were built decades ago. These legacy applications power essential business operations despite relying on outdated technologies and integration patterns. Although complete system replacement would be ideal, practical constraints such as budget limitations, resource availability, technical complexity, and missing documentation often make modernization efforts challenging.

This post first shows proxy architecture patterns to expose a legacy SOAP server over a REST API. It then shows how to integrate a legacy SOAP client with applications using a REST API.

While SOAP and REST APIs share HTTP as their foundation, SOAP has some limitations compared to REST, like limited HTTP methods (GET/POST only) and mandatory XML formatting. REST is more flexible with multiple HTTP methods and diverse payload formats (plain text, binary, HTML, JSON, XML).

Using API Gateway and Lambda to proxy SOAP service

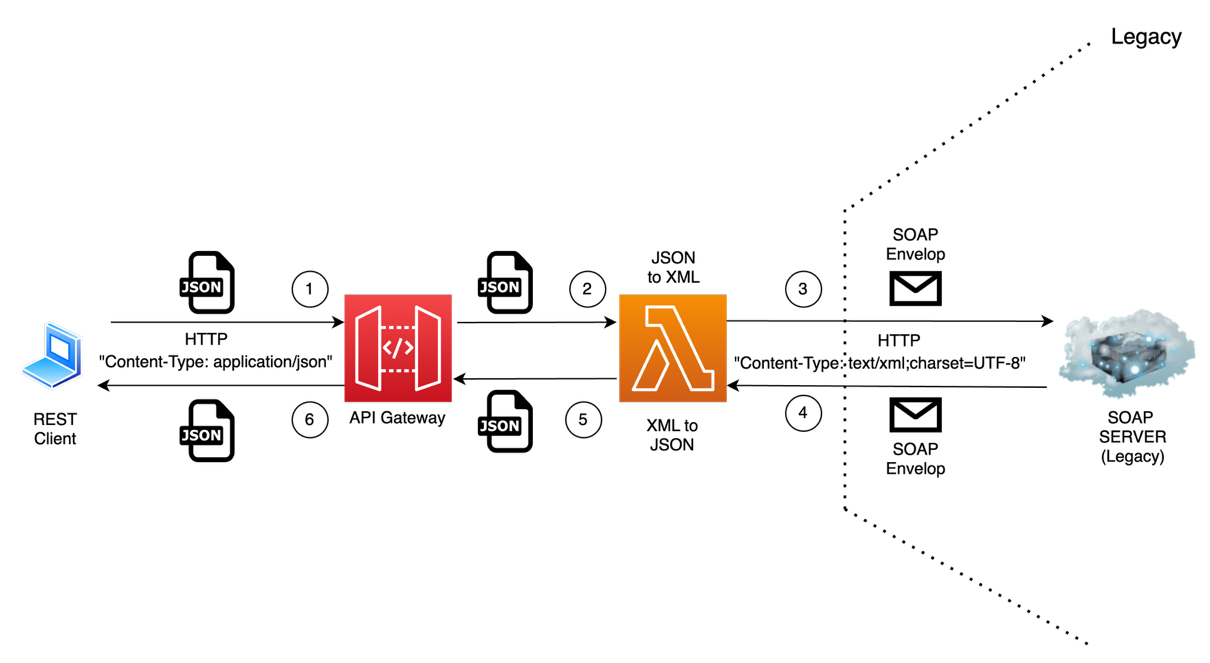
Consider a legacy solution that only supports SOAP. The following diagram shows the architecture for a SOAP proxy server using API Gateway and Lambda.

Figure 1: SOAP Server Proxy for modernized architecture

Figure 1: SOAP Server Proxy for modernized architecture

The proxy exposes the APIs hosted on the SOAP Server (on the right side of the image) over a REST interface. A SOAP service expects the HTTP Content-Type header set to text/xml, and a XML format payload that follows the WSDL specification defined by the server.

In the proposed architecture, the Lambda function is the core transformation engine, handling the bidirectional conversion between JSON and XML formats. Lambda functions can be developed in multiple programming languages such as Python, Node.js, Java, C#, Go, Ruby, and PowerShell, allowing you to use your existing development expertise. The serverless nature of Lambda provides automatic scaling to handle traffic spikes without needing infrastructure management or capacity planning.

API Gateway acts as the intelligent front door, managing all incoming requests and routing them appropriately. It provides enterprise-grade features such as request throttling to protect backend systems from overload, comprehensive authentication and authorization mechanisms, API key management for partner access control, request and response validation, caching capabilities for improved performance, and detailed monitoring and logging. These built-in features remove the need for custom middleware development and provide immediate operational benefits. API Gateway can receive multiple payload format such as XML, JSON, binary data, and plain text. This makes it suitable for diverse integration scenarios.

Using API Gateway and Lambda to support legacy SOAP clients

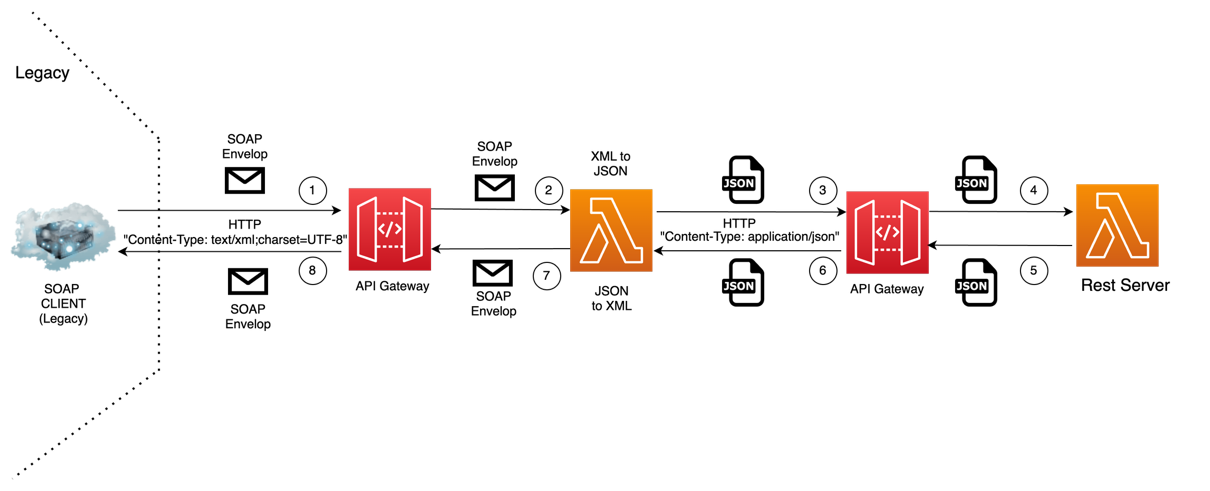
The previous section focused on exposing SOAP services over REST APIs. Organizations also face the reverse challenge where legacy SOAP client applications must access REST services. The architecture for supporting legacy SOAP clients follows a similar pattern but with reversed data flow. In this case, the legacy SOAP client sends XML-formatted requests to what it believes is a SOAP server. However, behind the scenes API Gateway and Lambda work together to translate these requests into REST API calls.

Figure 2: Legacy SOAP client modernization architecture

Figure 2: Legacy SOAP client modernization architecture

The legacy SOAP client application sends XML SOAP messages to API Gateway. The Lambda function receives these SOAP requests, extracts the relevant data from the XML envelope, and transforms it into JSON format for the modern REST service.

The Lambda function wraps the JSON response from the REST services into the SOAP XML format that the legacy client expects. It recreates the appropriate XML structure, SOAP headers, and ensures that the response conforms to the WSDL specification that the client application was designed to consume.

Example scenario

Let’s suppose our legacy client application needs to send a SOAP request to convert an integer number to its word form. The SOAP envelop to convert the number 1519 to its long form “one thousand, five hundred and nine” looks like this:

<?xml version="1.0" encoding="utf-8"?>
<soap:Envelope xmlns:soap="http://schemas.xmlsoap.org/soap/envelope/">
    <soap:Body> \
        <ConvertNumberToWordsSoapIn>
            <NumberToWordsRequest>1519</NumberToWordsRequest>
        </ConvertNumberToWordsSoapIn>
    </soap:Body>
</soap:Envelope>

The REST conversion service expects a JSON payload the as follownig:

jsonObject = {
	"data" : 1519
}

The following code block shows a sample Lambda function implementation for this. This function converts the SOAP XML envelop to JSON, changes the http header to application/json, and converts response from REST service to SOAP format.

var parseString = require('xml2js').parseString;
const axios = require('axios');

exports.handler = async (event, context) => {
    var valueNumber;
    
    try {
        console.log("Parsing XML string");

        // Parsing the XML to obtain data needed for conversion (number to words)
        parseString(event.body, function (err, result) {
            if (!err) {
                valueNumber = result['soap:Envelope']['soap:Body'][0]
                              ['ConvertNumberToWordsSoapIn'][0]
                              ['NumberToWordsRequest'][0];
            } else { 
                console.log (err);
                throw (err);
            }
        });
        console.log("Creating JSON for calling the service");
        // Creating JSON to call service
        var jsonObject = {
            "data" : valueNumber
        }
        
        console.log("Calling Microservice (NumberToWords)");
        const headers = { 
            'Content-Type': 'Application/json'
        };
        
        console.log ("Parameter for NumberToWords URL:" + 
                    JSON.stringify(process.env.NumberToWordMicroservice));

        // Calling numberToWords REST Server
        var resultNumberToWords = await 
            axios.post(process.env.NumberToWordMicroservice, jsonObject, { headers });
        
        // Creating the response
        console.log("Creating response XML");

        var resp =  create_response (JSON.stringify(resultNumberToWords.data.message));
        console.log("Response in XML: "+ resp);
        
        // Returning the value in XML using text/xml content type
        let response = {'statusCode': 200, headers: {"content-type": "text/xml"}, 
                        'body': JSON.stringify(resp)}
        return response;
        
    } catch (err) {
        console.log ("Error: " + err);
        let response = {'statusCode': 500, 
                        headers: {"content-type": "text/xml"}, 'body': err}
        return response;
    }
};

// Function to create a SOAP XML envelope with the result value
function create_response(numberInWords) {
  return '<?xml version="1.0" encoding="utf-8"?> \
            <soap:Envelope xmlns:soap="http://schemas.xmlsoap.org/soap/envelope/">\
            <soap:Body>\
              <m:ConvertNumberToWordsResponse xmlns:m="http://www.dataaccess.com/webservicesserver/"> \
                  <m:ConvertNumberToWordsResponseResult>' + numberInWords + '</m:ConvertNumberToWordsResponseResult> \
              </m:ConvertNumberToWordsResponse> \
            </soap:Body>\
            </soap:Envelope>';
}

With this approach, you can maintain your existing SOAP client applications without modification, allowing them to consume modern REST services. You can preserve investments in legacy client applications while gradually modernizing the overall system. This architecture is particularly valuable in scenarios where multiple legacy SOAP clients need to access the same modern REST services. This is because a single proxy can serve multiple client applications simultaneously. The serverless nature of the architecture makes sure that it scales automatically based on the number of client requests, providing cost-effective operation regardless of usage patterns.

Alternative approach using API Gateway transformation capabilities

The Lambda-based approach provides maximum flexibility and control. API Gateway also offers built-in transformation capabilities that can handle certain SOAP modernization scenarios without the need for compute resources.

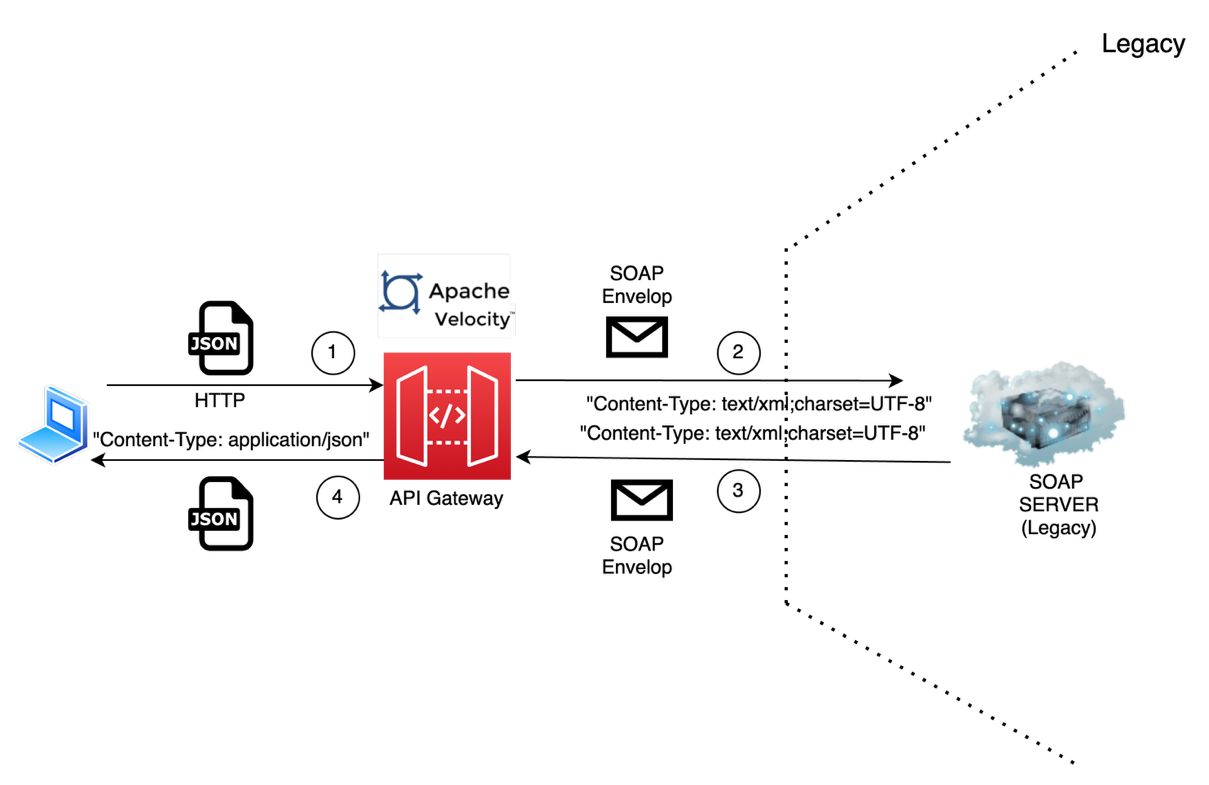
The native API Gateway transformation uses Apache Velocity Template Language mapping templates. It converts the payload directly at the gateway, offering a streamlined solution for specific modernization scenarios.

The VTL approach works by defining mapping templates that handle the conversion process between different payload formats. When modernizing SOAP services, these templates can intercept REST requests with JSON payloads, restructure the data into XML format compatible with your legacy SOAP endpoints, and reverse the process for responses returning to the client.

Figure 3: API Gateway with velocity template language transformation

Figure 3: API Gateway with velocity template language transformation

This gateway-native transformation strategy offers several operational advantages. You benefit from streamlined architecture because the transformation logic resides entirely within the API Gateway service. There are no other infrastructure components to manage or monitor, and the solution avoids the complexity of coordinating between multiple AWS services. Cost efficiency is another key benefit, as there are no compute charges beyond the standard API Gateway pricing.

Consider the previous example of converting a number to its word format. The VTL transformation in API Gateway will look like this:

## Parse the SOAP envelope and extract the number value
#set(\$xmlDoc = \$input.path('\$'))
#set(\$numberToWords = \$xmlDoc.Envelope.Body.ConvertNumberToWordsSoapIn.NumberToWordsRequest)

## Convert to integer if it's a string
#if(\$numberToWords.toString().matches("^\d+\$"))
  #set(\$dataValue = \$numberToWords.toInteger())
#else
  #set(\$dataValue = \$numberToWords)
#end

{
  "data": \$dataValue
}

You should consider VTL transformations when your SOAP services have predictable, stable schemas with relatively direct XML structures. This approach works particularly well for legacy systems that rarely undergo changes and have clear request-response patterns. For more dynamic environments or complex transformation requirements, the Lambda-based solution provides superior flexibility and maintainability.

Security considerations

An important consideration when working with legacy SOAP services is understanding their authentication mechanisms. SOAP protocols often implement authentication through security standards, where authentication credentials and security tokens are embedded directly within the SOAP envelope headers. This includes username tokens, digital signatures, and encryption elements that are part of the XML structure.

When SOAP envelopes contain unencrypted authentication information in the headers, the proxy architecture typically functions without more modifications. This is because the Lambda function can pass through these authentication elements transparently to the backend SOAP service. However, due to the nature of SOAP authentication being tightly integrated with the XML envelope structure, certain scenarios may need custom handling within the Lambda function.

For example, if the SOAP service uses timestamp-based authentication tokens, session management, or needs specific security header modifications, the Lambda function may need customization to properly handle, validate, or refresh these authentication elements during the JSON-to-XML transformation process. Organizations should carefully analyze their SOAP service authentication requirements to determine if more Lambda logic is needed to maintain security compliance.

Moreover, make sure that any SOAP authentication credentials processed by the Lambda function are handled securely and never logged in plain text.

Conclusion

In this post, you learned how cloud-native services can bridge the gap between legacy systems and modern application architectures, allowing you to use your existing investments while adopting contemporary development practices and technologies.

Amazon API Gateway and AWS Lambda enable organizations to create REST services that proxy legacy SOAP servers, allowing modern applications to consume legacy services through JSON payloads while preserving existing SOAP infrastructure. This serverless solution provides cost-effectiveness, automatic scaling, and reduced operational overhead while facilitating company modernization through scalable APIs without abandoning legacy software investments.

This modernization strategy allows you to gradually transition from legacy SOAP services to modern REST APIs without disrupting existing business operations. As your modernization journey progresses, you can extend this pattern to support more SOAP services or implement more sophisticated transformation logic based on your specific business requirements.

For more serverless learning resources, visit Serverless Land.

Orchestrating document processing with AWS AppSync Events and Amazon Bedrock

Post Syndicated from Mehdi Amrane original https://aws.amazon.com/blogs/compute/orchestrating-document-processing-with-aws-appsync-events-and-amazon-bedrock/

Many organizations implement intelligent document processing pipelines in order to extract meaningful insights from an increasing volume of unstructured content (such as insurance claims, loan applications and more). Traditionally, these pipelines require significant engineering efforts, as the implementation often involves using several machine learning (ML) models and orchestrating complex workflows.

As organizations integrate these pipelines to customer facing applications (such as web applications for customers to upload documents such as insurance claims, loan approval documents and more), they set goals to provide insights in real time to increase the end customer experience. These organizations also aim to run and scale these workloads with minimal operational overhead and optimizing on costs. In addition, these organizations require the implementation of common security practices such as identity and access management, to make sure that only authorized and authenticated users are allowed to perform specific actions or access specific resources.

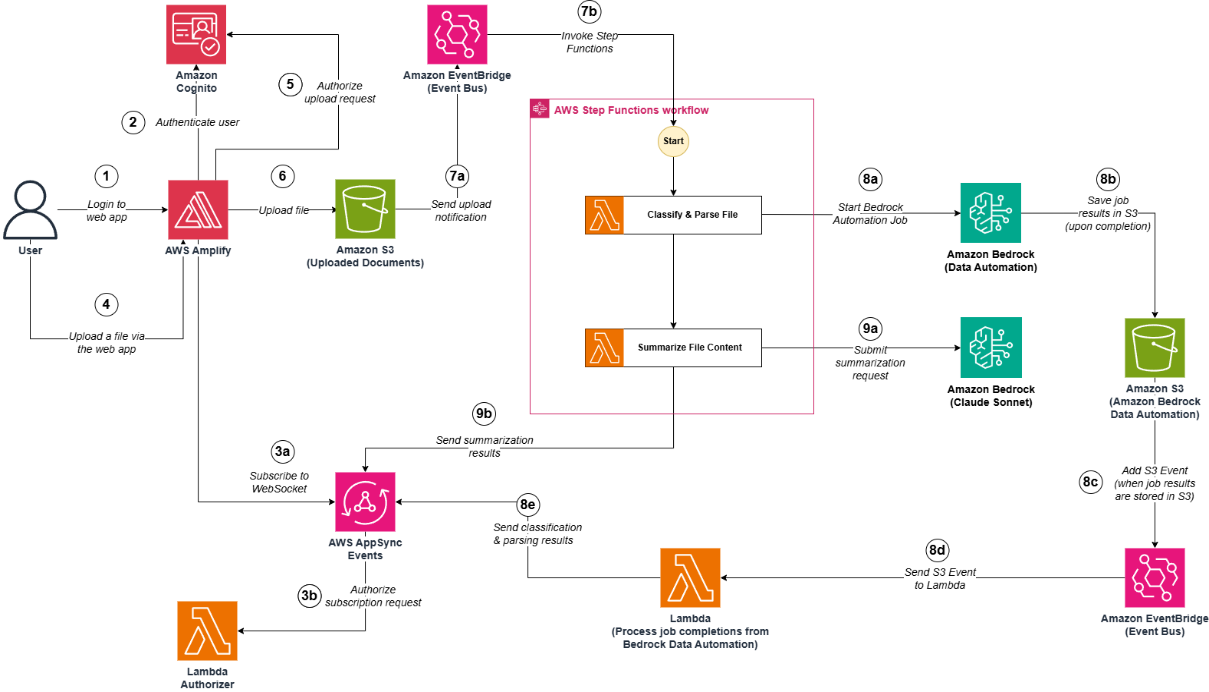
In this post, we show you a solution to simplify the creation of an intelligent document processing pipeline, with a web application for customers to upload their files (documents and images) and derive insights from it (summarization, fields extraction and classification). The solution primarily use serverless technologies, it includes a web socket to receive insights in real time and offers several benefits, such as automatic scaling, built-in high availability, and a pay-per-use billing model to optimize on costs. The solution also includes an authentication layer and an authorization layer to manage identities and permissions.

Solution overview

In this post, we provide an operational overview of the solution, and then describe how to set it up with the following services:

The solution architecture is illustrated in the following diagram:

Step 1: The user authenticates to the web application (hosted in AWS Amplify).
Step 2: Amazon Cognito validates the authentication details. After this, the user is now logged in the web application.
Steps 3aand 3b:

  • Step 3a: The web application (AWS Amplify) subscribes to an AWS AppSync Events web socket.
  • Step 3b: The AWS AppSync Events web socket calls an AWS Lambda authorizer to confirm that the user is authorized to subscribe to the web socket.

Step 4: The user uploads a file (document or image) using the web application.
Step 5: The web application (hosted in AWS Amplify) calls Amazon Cognito (identity pool) to confirm that the user is authorized to upload a file.
Step 6: The file is uploaded in an Amazon S3 bucket.
Steps 7a and 7b: Upon reception of an Amazon S3 upload event (which notifies that the file was uploaded in the Amazon S3 bucket) in the default Amazon Event Bridge bus, an Amazon Event Bridge bus rule triggers the execution of an AWS Step Functions state machine to start the orchestration workflow.
Step 8 (Step to extract fields from a file and classify it):

  • Step 8a: The first AWS Lambda function starts a new Amazon Bedrock Automation job (this job extracts specific fields from the uploaded file and classify it)
  • Step 8b: Once the job is completed, the results are stored in an Amazon S3 bucket.
  • Step 8c and 8d: Upon reception of an Amazon S3 event (which notifies that the results were stored in the Amazon S3 bucket) in the default Amazon Event Bridge, an Amazon Event Bridge bus rule triggers the execution of an AWS Lambda function
  • Step 8e: An AWS Lambda function publishes the results to the web socket.

Steps 9a and 9b: The second AWS Lambda function submits a prompt to an Amazon Bedrock foundation model (Sonnet 3), to request a summarization in streaming of the uploaded file. The AWS Lambda function publishes the streaming data to the web socket.

After Step 8e and Step 9b, the user can now consult the summarization result and extraction insights of the uploaded file in the web application.

Pre-requisites

To follow along and set up this solution, you must have the following:

  • An AWS account
  • A device with access to your AWS account with the following:
    • Python 3.12 installed (including pip)
    • Node.js 20.12.0 installed
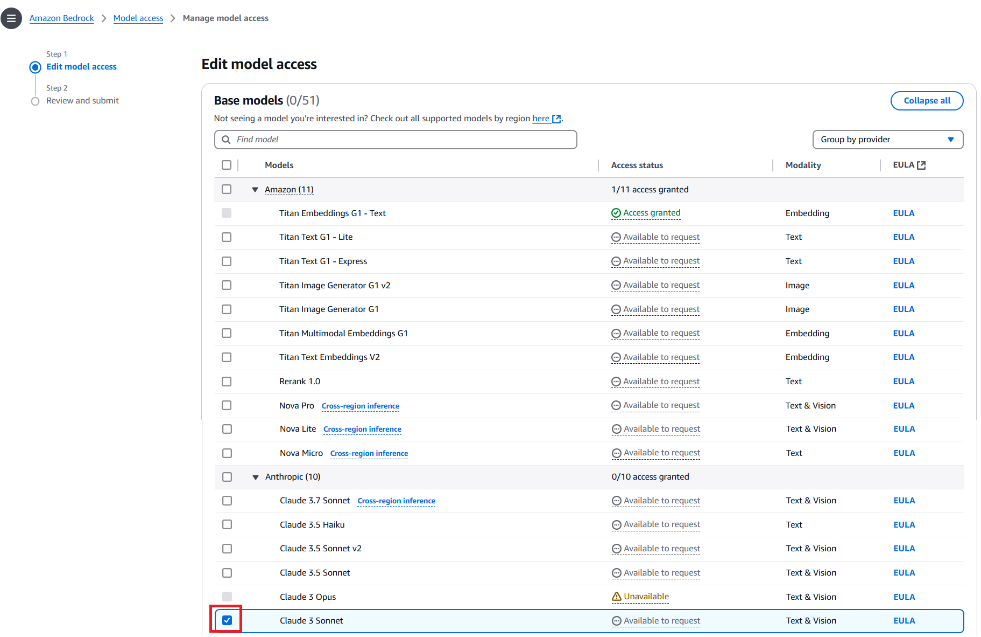
  • Enable Model Access to the Claude 3 Sonnet model in Amazon Bedrock


Note: Deploying this solution will incur costs. Review the pricing page of each AWS service used in this post for details on costs. The cost of running this solution will primarily depend on:

  • The number of documents (and the size of each document)
  • The number of active users

Setup Amazon Bedrock Data Automation

In this section, we setup an Amazon Bedrock Data Automation project and an Amazon Bedrock blueprint.

A project contains a list of blueprints, and each blueprint defines the fields to extract from different types of files (such as documents or images). In this post, we define a blueprint for a driving license.

Complete the following steps to create an Amazon Bedrock Data Automation project and a driving license blueprint:

  1. Clone the GitHub repository
    git clone https://github.com/aws-samples/sample-create-idp-with-appsyncevents-and-amazonbedrock.git

  2. Go to the sample-create-idp-with-appsyncevents-and-amazonbedrock folder
    cd sample-create-idp-with-appsyncevents-and-amazonbedrock

  3. Initialize the environment (make the shell script files, from the GitHub repository, ready to be used)
    chmod +x ./init-env.sh && source ./init-env.sh

  4. Run the script setup-bda-project.sh to create an Amazon Bedrock Data Automation project and a sample driving license blueprint:
    ./setup-bda-project.sh

Create the web socket and orchestration backend

In this section, we create the following resources:

  • A user directory for web authentication and authorization, created with an Amazon Cognito user pool. An Amazon Cognito identity pool is also created to validate that users are authorized to upload files via the web application.
  • A web socket using AWS AppSync Events. This allows our web application to receive real time updates for summarization and extraction results. An authorization layer is also created to protect the web socket from unauthorized users. This is implemented with a Lambda authorizer function to validate that incoming requests include valid authorization details.
  • A state machine using AWS Step Functions and AWS Lambda to orchestrate the summarization and extraction operations from the unstructured content
  • Amazon S3 buckets to store files for document processing, and code files for AWS Lambda functions

Complete the following steps to create the web socket and the orchestration backend of the solution, using AWS CloudFormation templates:

  1. Create Amazon S3 buckets used by the solution by running the following script. These buckets will store the files uploaded by users and code files of the AWS Lambda functions used in this solution.
    cd $CURRENT_DIR/s3; ./create-s3-buckets.sh

  2. Create the Amazon Cognito user pool and identity pool by running the create-cognito-userpool.sh script:
    cd $CURRENT_DIR/cognito; ./create-cognito-userpool.sh

  3. Create the AWS AppSync Events web socket by running the following script:
    cd $CURRENT_DIR/appsync/; ./create-appsync-api.sh

  4. Create the AWS Step Functions state machine (including AWS Lambda functions) by running the following scripts:
    cd $CURRENT_DIR/orchestration/; ./create-orchestration.sh

Configure the Amazon Cognito user pool

In this section, we create a user in our Amazon Cognito user pool. This user will log in to our web application.

Run the script create-cognito-testuser.sh to create the user (make sure to provide your email address):

cd $CURRENT_DIR/cognito; ./create-cognito-testuser.sh #your-email-address#

After you create the user, you should receive an email with a temporary password in this format: “Your username is #your-email-address# and temporary password is #temporary-password#.”

Keep note of these login details (email address and temporary password) to use later when testing the web application.

Create the web application

In this section, we build a web application using AWS Amplify and publish it to make it accessible through an endpoint URL.

Complete the following steps to create the web application:

  1. Run the script create-webapp.sh to create the web application with AWS Amplify:
    cd $CURRENT_DIR/amplify/; ./create-webapp.sh

  2. Run the script deploy.sh to deploy the web application
    cd $CURRENT_DIR/amplify/amplify-idp; ./deploy.sh

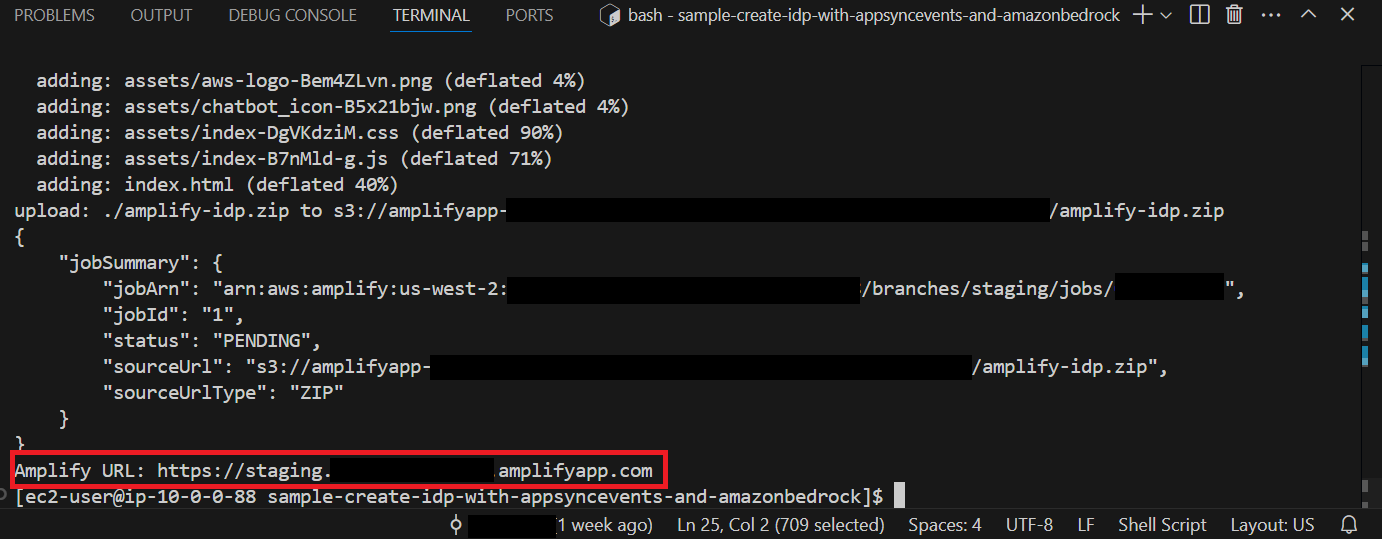
The web application is now available for testing and a URL should be displayed, as shown in the following screenshot. Take note of the URL to use in the following section.

Test the web application

In this section, we test the web application and upload a file to be processed:

  1. Open the URL of the AWS Amplify application in your web browser.
  2. Enter your login information (your email and the temporary password you received earlier while configuring the user pool in Amazon Cognito) and choose Sign in.
  3. When prompted, enter a new password and choose Change Password.
  4. You should now be able to see a web interface.
  5. Download the sample driving license at this location and upload it via the web application using either your camera or a file in your local device, as illustrated

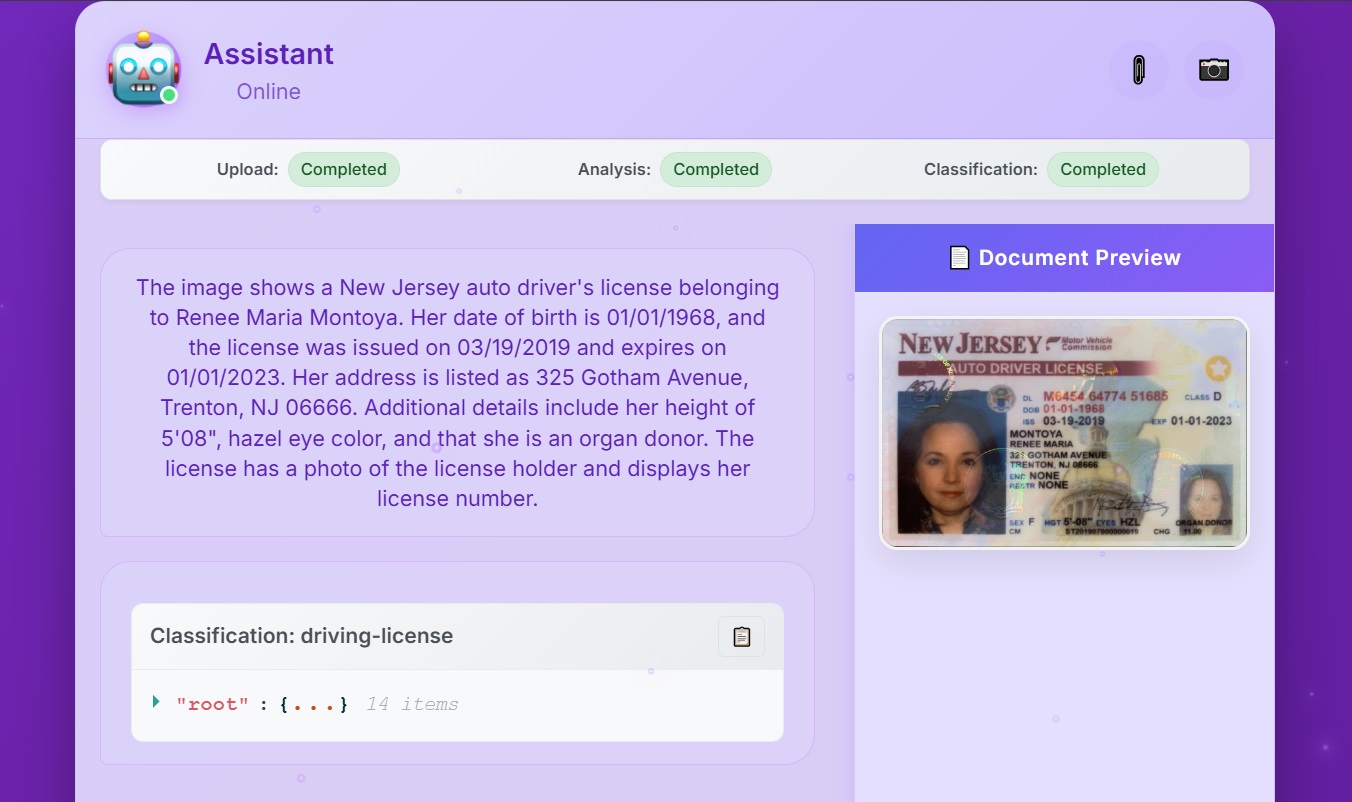
Once the file is uploaded, you should start receiving responses in the web application. When all the operations are completed, you should see a result equivalent to what is shown in the following screenshot:

Note: If you are planning to use other driving license sample images with other formats, you may have to update the existing Bedrock Data Automation blueprint we created earlier or define a new blueprint in your Bedrock Data Automation project we created earlier for these new images to work. For more information, please review the Bedrock Data Automation documentation.

Clean up

To make sure that no additional cost is incurred, remove the resources provisioned in your account. Make sure you’re in the correct AWS account before deleting the following resources.

Important note: You should exercise caution when performing the preceding steps. Make sure you are deleting the resources in the correct AWS account.

You can either navigate to the AWS CloudFormation console to delete the CloudFormation stacks associated to the resources provisioned or use the cleanup helper script cleanup.sh available at the root of the sample-create-idp-with-appsyncevents-and-amazonbedrock folder:

./cleanup.sh #region#

Conclusion

In this post, we walked through a solution to create a document processing pipeline, with a web application using serverless services. Via the web application, we were able to upload a file and receive responses in real time for different types of operations (summarization, extraction of specific fields and classification). First, we created an Amazon Bedrock Data Automation project (with a driving license blueprint). Then we created a web socket along with an orchestration solution using a state machine (AWS Step Functions and AWS Lambda functions). We also configured a user pool to grant a user access to the web application. Finally, we created the frontend of the web application in AWS Amplify.

To dive deeper into this solution, a self-paced workshop is available in AWS Workshop Studio.

Serverless ICYMI Q2 2025

Post Syndicated from Julian Wood original https://aws.amazon.com/blogs/compute/serverless-icymi-q2-2025/

Welcome to the 29th edition of the AWS Serverless ICYMI (in case you missed it) quarterly recap. At the end of a quarter, we share the most recent product launches, feature enhancements, blog posts, videos, live streams, and other interesting things that you might have missed!

In case you missed our last ICYMI, check out previous ICYMI posts.


Figure 1: Serverless calendar Q2 2025

Model Context Protocol (MCP)

MCP and agents are the hot topics in generative AI. MCP is an open protocol that standardizes how AI models can, in a secure and structured way, access external tools, data sources, and APIs. Amazon Q Developer IDE plugins and CLI both support MCP.

For a primer on MCP, watch What is MCP? No, Really!

AWS Serverless MCP Server

AWS announced the open-source AWS Serverless Model Context Protocol (MCP) Server, now available in the AWS Labs GitHub repository.


Figure 2: AWS Serverless MCP Server giving Lambda guidance

This is a tool that combines AI assistance with serverless expertise to enhance how developers build modern applications. The tool works with popular AI coding assistants like Amazon Q Developer and CLI, Cline, and Cursor. To add the MCP server, add the following code to your MCP client configuration.

{
  "mcpServers": {
    "awslabs.aws-serverless-mcp": {
      "command": "uvx",
      "args": [
        "awslabs.aws-serverless-mcp-server@latest"
      ],
      "env": { 
        "AWS_PROFILE": "your-aws-profile",
        "AWS_REGION": "us-east-1",
        "FASTMCP_LOG_LEVEL": "ERROR"
      }
    }
  }
}

The MCP server includes tools for project initialization, building and deployment, observability, and troubleshooting. The tool helps with operational excellence through observability features and provides contextual guidance for infrastructure as code decisions and AWS Lambda-specific best practices. This makes it easier for both new and experienced developers to build serverless applications.

There is also an Amazon ECS MCP Server to containerize and deploy applications to Amazon ECS within minutes. It helps configure all relevant AWS resources, including load balancers, networking, auto-scaling, monitoring, Amazon ECS task definitions, and services.

Amazon Aurora DSQL is now generally available


Figure 3: Amazon Aurora DSQL announcement

Amazon Aurora DSQL is now generally available. DSQL is a serverless, distributed SQL database with active-active high availability and multi-Region strong consistency. It is designed to make scaling and resilience effortless for your applications and offers the fastest distributed SQL reads and writes.

AWS Lambda

AWS Lambda Hackathon

The AWS Lambda Hackathon ran through June. With a total prize pool of $15,000, more than 3,700 participants competed to build Lambda applications that solve real-world business problems.


Figure 4: AWS Lambda Hackathon

Submissions needed to include a public code repository, a detailed README explaining the Lambda implementation, and a video demonstration. The projects are being judged by AWS experts based on the quality of the idea, architecture and design, and completeness of the solution.

Native support for Avro and Protobuf with Kafka

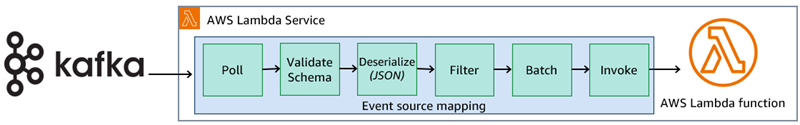
AWS Lambda now provides native support for Apache Avro and Protocol Buffers (Protobuf) formatted events with Apache Kafka event source mapping (ESM) when using Provisioned Mode.


Figure 5: Kafka processing flow diagram

The support allows you to validate your schema with popular schema registries. This allows you to use and filter the more efficient binary event formats and share data using schema in a centralized and consistent way. The ESM automatically validates incoming events against registered schemas and can deliver data in either the original binary format or as clean JSON, making it easier to build Kafka consumers across multiple programming languages.

Lambda logging changes can reduce Lambda CloudWatch logging costs. Lambda has introduced tiered pricing for CloudWatch logs and support for additional logging destinations, providing developers with more cost-effective logging options and greater flexibility in where they send their Lambda function logs.

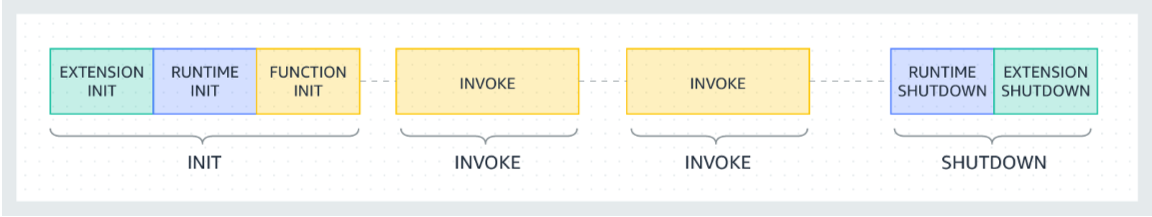
Lambda has standardized billing for the INIT phase, providing more predictable and transparent pricing for function initialization costs.


Figure 6: AWS Lambda lifecycle

This improvement is part of an ongoing effort to make serverless pricing more transparent and predictable for customers building production applications.

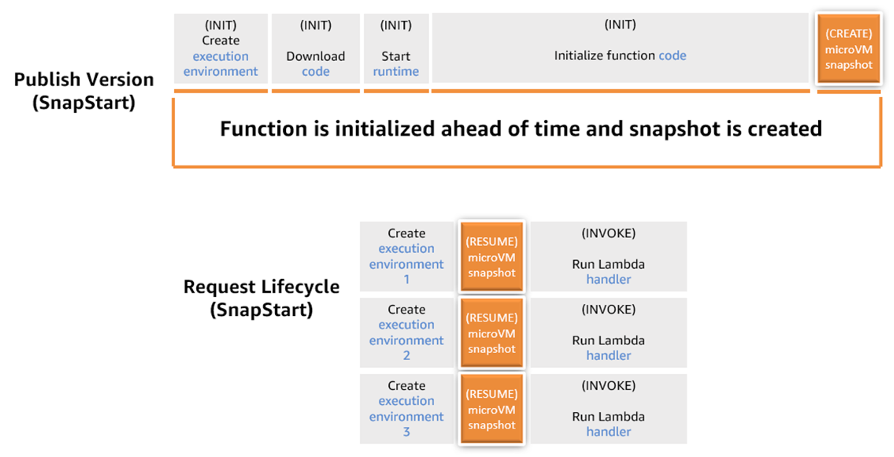
There is a new guide exploring priming strategies with SnapStart to optimize cold start performance for Java Lambda functions. SnapStart delivers up to 10x faster function startup performance at no extra cost by creating and caching a snapshot of the initialized execution environment.


Figure 7: AWS Lambda SnapStart lifecycle

Learn how to monitor network traffic in Lambda functions to improve security and performance visibility. The post provides strategies for gaining visibility into network behavior. The guidance covers tools, techniques, and best practices for implementing network monitoring that can help identify security threats, performance bottlenecks, and compliance issues.

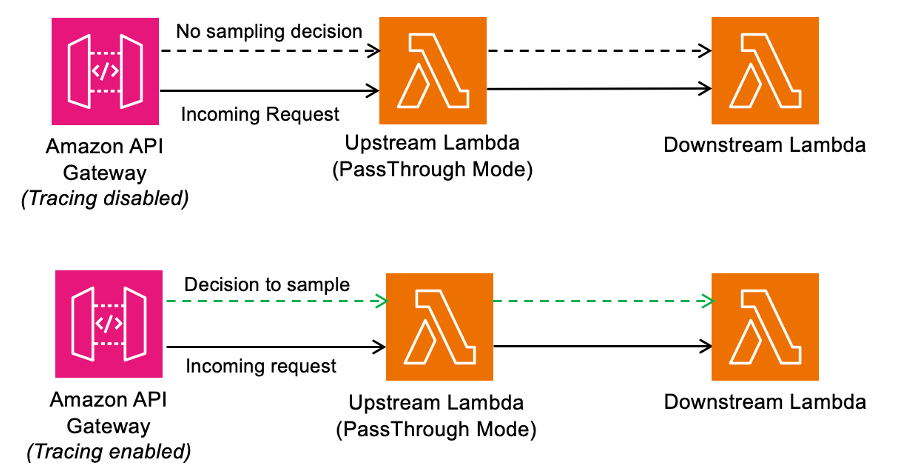
See how to optimize trace sampling behavior for Lambda functions using AWS X-Ray to improve observability while reducing costs and performance overhead.


Figure 8: AWS X-Ray tracing flow

This post provides guidance on implementing intelligent sampling strategies that provide the visibility needed for troubleshooting and optimization while minimizing overhead.

AWS CodePipeline now supports deploying to Lambda with traffic shifting for easier publishing of Lambda function revisions and traffic-shifting strategies for safer releases.

AWS named a Leader in Forrester Wave

AWS has been recognized as a Leader in The Forrester Wave: Serverless Development Platforms, Q2 2025, achieving the highest ranking in both the Current Offering and Strategy categories. This underscores AWS’s commitment to providing best-in-class innovation and developer experience in serverless application development. The evaluation analyzed key services, including AWS Lambda for serverless compute, AWS Step Functions and Amazon EventBridge for application integration, and AWS Fargate with Amazon ECS for serverless containers.

Amazon ECS

Amazon ECS now allows you to roll back your Amazon ECS service to a previous safe state if a deployment fails. Deployment circuit breaker automatically detects task launch failures while CloudWatch alarms allow you to detect issues that result in degradation in infrastructure.

Amazon ECS is also introducing a new account setting, defaultLogDriverMode. This allows you to define whether tasks in your account use blocking or non-blocking log driver mode by default, when you do not specify or omit it in your applications’ Task Definitions.

Amazon API Gateway

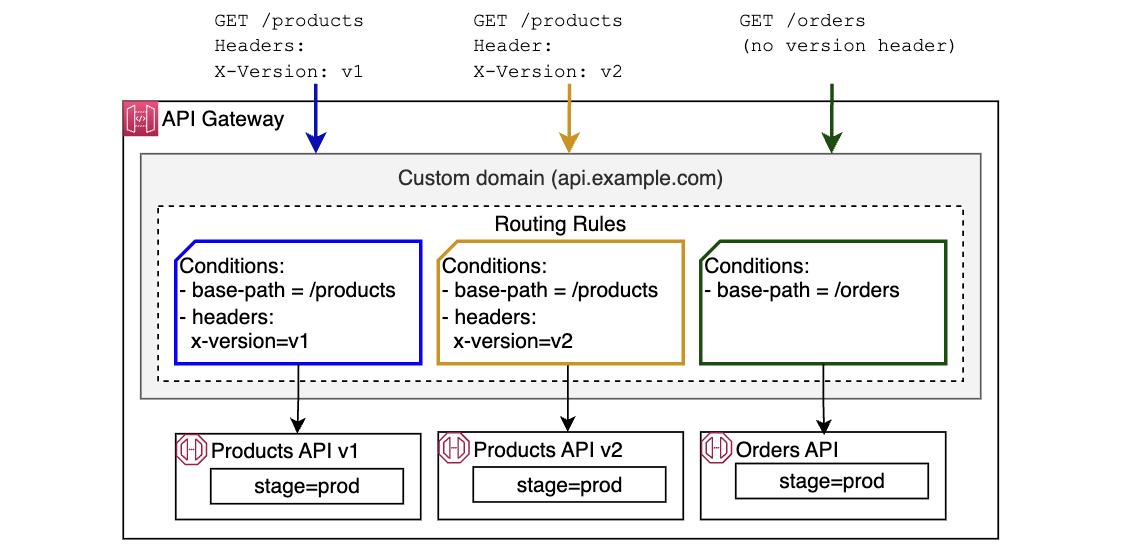
Amazon API Gateway now supports dynamic routing rules for custom domain name. This allows you to route API requests based on HTTP header values, either independently or in combination with URL paths. You can implement sophisticated routing strategies, such as API versioning, A/B testing, and gradual rollouts, without modifying existing API endpoints.


Figure 9: Amazon API Gateway dynamic routes

Learn how to use Amazon API Gateway to power hybrid workloads to more easily connect cloud and on-premises resources. There are practical examples of authentication, authorization, and data transformation patterns that are important for successful hybrid implementations.

AWS Serverless Application Model (AWS SAM) now supports custom domain names for private REST APIs feature of API Gateway.

Amazon EventBridge

Learn how to use Amazon EventBridge Pipes to enrich and customize notifications for more flexible and powerful event processing capabilities. The enhanced notification features allow you to create sophisticated event-driven workflows that can transform, filter, and route events based on complex business logic.

The EventBridge connector for Apache Kafka Connect is now generally available. This open-source connector streamlines event integration of Kafka environments with dozens of AWS services and partner integrations without writing custom integration code or running multiple connectors for each target.

EventBridge now supports AWS CodeBuild batch builds as a target. EventBridge Archive and Replay and API destinations connections now supports Customer Managed Keys.

Discover how to simplify private API integrations using EventBridge and AWS Step Functions. This guide covers the architectural patterns and implementation strategies required to build private integrations. The integrations maintain security while providing the flexibility and scalability that modern applications require.

Both Amazon SQS and Amazon SNS now support IPv6 for API requests, enabling you to communicate with SQS and SNS with IPv6, IPv4, or dual stack clients using public endpoints.

This Amazon S3 security guide covers best practices for securing S3 presigned URLs. Presigned URLs are a common pattern in serverless applications for providing temporary access to S3.

Discover how to enhance multi-account activity monitoring using event-driven architectures for better security and compliance across complex AWS environments.

Generative AI

You can more easily use Amazon Q to transform and upgrade Java and .NET applications.

Amazon Q Developer users with AWS Builder IDs can more easily upgrade to the Pro Tier, giving them higher usage limits in their IDEs and on the CLI.

Amazon Q Developer Eclipse IDE plugin is available and an agentic coding experience is now available within JetBrains and Visual Studio.

Amazon Bedrock now offers comprehensive CloudWatch metrics support for Agents.

Powertools for AWS Lambda introduces Bedrock Agents Function utility. This helps to create Lambda functions that can respond to Amazon Bedrock Agent action requests with built-in parameter injection, response formatting, eliminating boilerplate code and accelerating development.

Amazon Bedrock Intelligent Prompt Routing is now generally available. This routes prompts to different foundation models within a model family, helping you optimize for quality of responses and cost.

Prompt caching helps reduce costs by up to 90% and latency by up to 85% by caching frequently used prompts across multiple API calls. Prompt caching is now generally availability on Amazon Bedrock.

Serverless Compute Blog Posts

April

May

June

Serverless Office Hours weekly livestream

April

May

June

The Serverless landing page has more information. The Lambda resources page contains case studies, webinars, whitepapers, customer stories, reference architectures, and even more Getting Started tutorials.

You can also follow the Developer Advocacy team members who work on Serverless to see the latest news, follow conversations, and interact with the team.

And finally, visit the Serverless Land for all your serverless needs.

Building serverless event streaming applications with Amazon MSK and AWS Lambda

Post Syndicated from Tarun Rai Madan original https://aws.amazon.com/blogs/big-data/building-serverless-event-streaming-applications-with-amazon-msk-and-aws-lambda/

As organizations build modern applications with event-driven architectures (EDA), they often seek solutions that minimize infrastructure management overhead while maximizing developer productivity. Amazon Managed Streaming for Apache Kafka (Amazon MSK) and AWS Lambda together provide a serverless, scalable, and cost-efficient platform for real-time event-driven processing.

In this post, we describe how you can simplify your event-driven application architecture using AWS Lambda with Amazon MSK. We demonstrate how to configure Lambda as a consumer for Kafka topics, including a cross-account setup and how to optimize price and performance for these applications.

Why use Lambda with Amazon MSK?

Customers building event-driven applications have several key priorities when it comes to their architecture choices. They typically seek to reduce their operational overhead by using Amazon Web Services (AWS) to handle the complex, underlying infrastructure components so their teams can focus on core business logic. Additionally, developers prefer a streamlined experience that minimizes the need for repetitive boilerplate code, enabling them to be more productive and focus on creating value. Furthermore, these customers want to achieve both scalability and cost-effectiveness without the burden of managing compute infrastructure directly. Lambda integration with Amazon MSK effectively addresses these requirements, delivering a comprehensive solution that combines the benefits of serverless computing with managed Kafka services. For example, an ecommerce company can use Amazon MSK to collect real-time clickstream data from its website and process those events using AWS Lambda. With this integration, they can trigger Lambda functions to update recommendation models, send personalized offers, or analyze user behavior instantly—without provisioning or managing servers. The key benefits of using Lambda with Amazon MSK include:

  1. Simplicity through native integration – AWS Lambda offers native integration with Amazon MSK through a connector resource called event source mapping. You can use this integration to directly associate a Kafka topic—whether it’s on Amazon MSK or a self-managed Kafka cluster—as an event source for a Lambda function without writing custom consumer logic. With just a few configuration steps, event source mapping handles partition assignment, offset tracking, and parallelized batch processing under the hood. It uses the Kafka consumer group protocol to distribute topic partitions across multiple concurrent Lambda invocations, supports batch windowing, and enables at-least-once delivery semantics. Moreover, it automatically commits offsets upon successful function execution while handling retries and dead-letter queue (DLQ) routing for failed records, significantly reducing the operational overhead traditionally associated with Kafka consumers.
  2. Auto scaling and throughput controls – When using AWS Lambda with Amazon MSK through event source mapping, Lambda automatically scales by assigning a dedicated event poller per Kafka partition, enabling parallel, partition-based processing. This allows the system to elastically handle varying traffic without manual intervention. For advanced control, provisioned concurrency pre-initializes Lambda execution environments, eliminating cold starts and delivering consistent low-latency performance. Additionally, with provisioned event source mapping, you can configure the minimum and maximum number of Kafka pollers, providing precise control over throughput and concurrency. This is ideal for applications with unpredictable traffic patterns or strict latency requirements.
  3. Cost-effectiveness – AWS Lambda uses a pay-per-use model in which you only pay for compute time and number of invocations. When integrated with Amazon MSK, there are no charges for idle time, making it ideal for bursty or low-frequency Kafka workloads. You can further optimize costs by tuning batch size and batch window settings. For mission-critical workloads, provisioned concurrency provides consistent performance with controlled pricing.
  4. Event filtering – AWS Lambda supports event filtering for Amazon MSK event sources, which means you can process only the Kafka records that match specific criteria. This reduces unnecessary function invocations and optimizes your function costs. You can define up to five filters per event source mapping (with the option to request an increase to ten). Each filter uses a JSON-based pattern to specify the conditions a record must meet to be processed. Filters can be applied using the AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS Serverless Application Model (AWS SAM) templates. For more details and examples, refer to the AWS Lambda documentation on event filtering with Amazon MSK.
  5. Handling Availability Zone outage for your consumer – Amazon MSK enables high availability for your Kafka brokers by distributing them across multiple Availability Zones within a Region. To maintain high availability across your application, you similarly need a consumer that offers high availability. AWS Lambda offers high availability and resilience by running your consumer functions across multiple Availability Zones in a Region. This means that even if one Availability Zone experiences an outage, your Lambda function will continue to operate in other healthy Availability Zones. While Lambda manages security patching and Availability Zone failure scenarios, you can focus on your application logic.
  6. Cross-account event processing – Cross-account connectivity between AWS Lambda and Amazon MSK allows a Lambda function in one AWS account to consume data from an MSK cluster in another account using MSK multi-VPC private connectivity powered by AWS PrivateLink. This setup is particularly beneficial for organizations that centralize Kafka infrastructure while maintaining separate accounts for different applications or teams.
  7. Support for JSON, Avro, Protobuf, and Schema Registries – AWS Lambda supports Kafka events in JSON, Avro and Protobuf formats via event source mapping. It integrates with AWS Glue Schema registry, Confluent Cloud Schema registry, and self-managed Confluent Schema registry , enabling native schema validation, filtering, and deserialization without custom code.

How Lambda processes messages from your Kafka topic

Lambda uses event source mappings to process records from Amazon MSK by actively polling Kafka topics through event pollers that invoke Lambda functions with batches of records. These mappings are Lambda managed resources designed for high-throughput, stream-based processing. By default, Lambda detects the OffsetLag for all partitions in your Kafka topic and automatically scales pollers based on traffic. For high-throughput applications, you can enable provisioned mode to define minimum and maximum pollers, and your event source mapping auto scales between the minimum and maximum defined values. In the provisioned mode, each poller can process up to 5 MBps and supports concurrent Lambda invocations.

After Lambda processes each batch, it commits the offsets of the messages in that batch. If your function returns an error for a message in a batch, Lambda retries the whole batch of messages until processing succeeds or the messages expire. You can send records that fail all retry attempts to an on-failure destination for later processing. To maintain ordered processing within a partition, Lambda limits the maximum event pollers to the number of partitions in the topic. When setting up Kafka as a Lambda event source, you can specify a consumer group ID to let Lambda join an existing Kafka consumer group. If other consumers are active in that group, Lambda will receive only part of the topic’s messages. If the group exists, Lambda starts from the group’s committed offset, ignoring the StartingPosition. The following diagram illustrates this flow.

Walkthrough: Build a serverless Kafka app with AWS Lambda

Follow these steps to build a serverless application that consumes messages from an MSK cluster using AWS Lambda:

  1. Create an Amazon MSK cluster. Use the AWS Management Console or AWS CLI to create your MSK cluster. When the cluster is up, create your Kafka topic(s). For detailed instructions, refer to the Amazon MSK documentation.
  2. Create a Lambda function using the AWS Management Console or the AWS CLI. To learn more about creating a Lambda function, refer to Create your first Lambda function. The Lambda function’s execution role needs to have the following permissions:
    1. Access to connect to your MSK cluster
    2. Permissions to manage elastic network interfaces in your VPC
  3. To connect Lambda to Amazon MSK as a consumer, set up event source mapping to link your MSK topic with the Lambda function. This allows Lambda to automatically poll for new messages and process them. Follow the guide on how to configure event source mapping.

For reference, configuring event source mapping involves three steps:

  1. Network setup – In the default event source mapping mode, you need to configure a networking setup using a PrivateLink endpoint or NAT gateway for event source mapping to invoke Lambda functions. In provisioned mode, no networking configuration is needed (and you don’t incur the cost of networking components).
  2. Event source mapping parameter configuration – This involves setting necessary configuration parameters for the event source mapping to be able to poll messages from your Kafka cluster. This includes the MSK cluster, topic name, consumer group ID, authentication method, and optionally, schema registry, scaling mode. You can configure the scaling mode for provisioned throughput, along with batch size, batch window, and event filtering for your event source mapping.
  3. Access permissions – This involves configuring required permissions to access the required AWS resources, and includes configuring permissions for the function to execute the code, permissions for the event source mapping to access your MSK cluster, and permissions for Lambda to access your VPC resources.

The following screenshot shows the console setup for configuring Amazon MSK event source mapping, including the Amazon MSK trigger related fields.

The following screenshot shows event poller configuration.

The following screenshot shows additional settings you can use, depending on your use case.

Optimizing AWS Lambda for stream processing with Amazon MSK

When building real-time data processing pipelines with Amazon MSK and AWS Lambda, it’s important to tune your setup for both performance and cost-efficiency. Lambda offers powerful serverless compute capabilities, but to get the most out of it in a streaming context, you need to make a few key optimizations:

  1. Enable provisioned concurrency for low-latency processing – For workloads that are sensitive to latency—cold starts can introduce unwanted delays. By enabling provisioned concurrency, you can pre-warm a specified number of Lambda instances so they’re always ready to handle traffic immediately. This eliminates cold starts and provides consistent response times, which is crucial for latency-critical use cases.
  2. Enable provisioned mode for event source mapping for high-throughput processing – For Kafka workloads with stringent throughput requirements, activate the provisioned mode. The optimal configuration of minimum and maximum event pollers for your Kafka event source mapping depends on your application’s performance requirements. Start with the default minimum event pollers to baseline the performance profile and adjust event pollers based on observed message processing patterns and your application’s performance requirements. For workloads with spiky traffic and strict performance needs, increase the minimum event pollers to handle sudden surges. You can fine-tune the minimum event pollers by evaluating your desired throughput, your observed throughput, which depends on factors such as the ingested messages per second and average payload size, and using the throughput capacity of one event poller (up to 5 MB/s) as reference. To maintain ordered processing within a partition, Lambda caps the maximum event pollers at the number of partitions in the topic.
  3. Optimize message batching using size and windowing – By integrating Lambda with Amazon MSK, you can control how messages are batched before they’re sent to your function. Tuning parameters such as batch size (the number of records per invocation: 1–10,000 records) and maximum batching window (how long to wait for a full batch: 0–300 seconds) can significantly impact performance. Larger batches mean fewer invocations, which reduces overhead and improves throughput. However, it’s important to strike a balance—too large a batch or window might introduce unwanted processing delays. Monitor your stream’s behavior and adjust these settings based on throughput requirements and acceptable latency.
  4. Apply filters to reduce unnecessary invocations – Not every record in your Kafka topic might require processing. To avoid unnecessary Lambda invocations (and associated costs), apply filtering logic directly when configuring the event source mapping. With Lambda, you can define filtering (up to 10 filters) criteria so that only relevant records trigger your function. This helps reduce compute time, minimize noise, and optimize your budget, especially when dealing with high-throughput topics with mixed content. For Amazon MSK, Lambda commits offsets for matched and unmatched messages after successfully invoking the function.

Conclusion

By combining Amazon MSK with AWS Lambda, you can seamlessly build modern, serverless event-driven applications. This integration eliminates the need to manage consumer groups, compute infrastructure, or scaling logic so teams can focus on delivering business value faster.

Whether you’re integrating Kafka into microservices, transforming data pipelines, or building reactive applications, Lambda with Amazon MSK is a powerful and flexible serverless solution. For detailed documentation on how to configure Lambda with Amazon MSK, refer to the AWS Lambda Developer Guide. For more serverless learning resources, visit Serverless Land.


About the Authors

Tarun Rai Madan is a Principal Product Manager at Amazon Web Services (AWS). He specializes in serverless technologies and leads product strategy to help customers achieve accelerated business outcomes with event-driven applications, using services like AWS Lambda, AWS Step Functions, Apache Kafka, and Amazon SQS/SNS. Prior to AWS, he was an engineering leader in the semiconductor industry, and led development of high-performance processors for wireless, automotive, and data center applications.

Masudur Rahaman Sayem is a Streaming Data Architect at AWS with over 25 years of experience in the IT industry. He collaborates with AWS customers worldwide to architect and implement sophisticated data streaming solutions that address complex business challenges. As an expert in distributed computing, Sayem specializes in designing large-scale distributed systems architecture for maximum performance and scalability. He has a keen interest and passion for distributed architecture, which he applies to designing enterprise-grade solutions at internet scale.

AWS named a Leader in the 2025 Forrester Wave: Serverless Development Platforms

Post Syndicated from Florence Chao original https://aws.amazon.com/blogs/compute/aws-named-a-leader-in-the-2025-forrester-wave-serverless-development-platforms/

Amazon Web Services (AWS) has been recognized as a Leader in The Forrester Wave: Serverless Development Platforms, Q2 2025, achieving the highest ranking in both the Current Offering and Strategy categories.

The Forrester Wave evaluation provides business leaders with rigorous, fact-based analysis for technology purchasing decisions. Through transparent criteria spanning current offering, strategy, and customer feedback, Forrester evaluates vendors to identify Leaders, Strong Performers, and Contenders. The AWS serverless portfolio unifies traditional and AI-driven development, enabling teams to build intelligent, adaptive systems with minimal infrastructure and code overhead. The evaluation analyzed across key services, including AWS Lambda for serverless compute, AWS Step Functions and Amazon EventBridge for application integration, and AWS Fargate with Amazon Elastic Container Service (Amazon ECS) for serverless containers.

Serverless beyond function-as-a-service

The serverless operating model has evolved beyond function-as-a-service approaches. It has become a comprehensive cloud-based software development model that abstracts away underlying cloud infrastructure, complex server configurations, runtime characteristics, and deployment patterns from the development process. Forrester defines key characteristics of serverless development platforms as supporting the deployment of arbitrary business logic, decoupled state from the underlying compute, autonomous scale by demand (often back to zero), flexible consumption-based billing, abstraction of the underlying cloud infrastructure, and event-driven communication.

According to the Forrester report, “AWS provides a mature foundation for event-driven application development with extensive integrations across the AWS ecosystem. AWS continues to evolve its serverless portfolio for market demands including the growing influence of AI workloads. AWS’s platform completeness and integration depth are notable, making it well-suited for organizations seeking to build production-grade event-driven applications at scale with granularity and control.”

AWS capabilities recognized in the report

AWS’s recognition as a Leader in this report underscores, for us, our commitment to providing best-in-class innovation and developer experiences in serverless application development. Findings from AWS’s vendor profile in the report include:

  • Strategy – AWS has a clear and cohesive vision that aligns serverless capabilities across its expansive cloud portfolio. Its innovation strategy is tightly coupled with customer feedback and reinforced through sustained R&D investment.
  • Capabilities – AWS offers strong capabilities across developer experiences, tools, and service integrations. Developers benefit from mature software development kits (SDKs), command line interface (CLI) tools, and infrastructure as code (IaC) options. Its APIs and event-driven integrations are among the best, enabling complex, scalable architectures and workflows.

Evolving serverless developer experience on AWS

AWS has made significant investments to streamline the developer onboarding experience through comprehensive resources and tools. As generative AI infuses every step of software development and transforms the technology landscape, organizations must adapt quickly to maintain their competitive edge. Many are building distributed architectures that use specific large language models (LLMs) based on unique requirements, and the serverless operating model is ideal for these AI-powered applications. Serverless enables organizations to start small and scale seamlessly while handling distributed, event-driven workflows securely at scale.

The newly launched AWS Serverless Model Context Protocol (MCP) server provides AI-powered, contextual guidance throughout the serverless development lifecycle, so developers can receive real-time assistance with service selection, best practices, and implementation patterns while building applications with Lambda. The developer-first approach also includes the Amazon Q Developer plugin for AI-assisted development (including code generation, debugging, and architectural guidance), enhanced AWS SAM CLI capabilities for improved local testing and debugging, the integration with Serverless Land for direct blueprint access on the Lambda console, extensive documentation with practical examples, interactive tutorials, and integration with familiar development environments. AWS has also enhanced the getting started experience through simplified deployment workflows, IaC templates, and automated best practices enforcement. Furthermore, the broad ecosystem of AWS partners, developer advocates, and community contributors provides additional support through workshops, sample applications, and reference architectures. These comprehensive improvements demonstrate our commitment to accelerating serverless adoption by making development more intuitive, efficient, and accessible for teams at any stage of their cloud journey.

Conclusion

AWS has been recognized as a Leader in the Forrester Wave: Serverless Development Platforms, Q2 2025, receiving top scores in Current Offering and Strategy categories, which, in our opinion, underscores our commitment to innovation and excellence in serverless computing. As the serverless landscape continues to evolve, AWS remains at the forefront, providing a comprehensive suite of services that enable developers to build scalable, efficient, and intelligent applications.As we look to the future, AWS will continue to invest in serverless technologies, pushing the boundaries of what’s possible in cloud computing. Whether you’re building AI-powered applications, modernizing legacy systems, or creating entirely new digital experiences, AWS serverless offerings provide the agility, scalability, and innovation you need to stay ahead in a rapidly evolving digital landscape.

Read the full report to learn why Forrester positioned AWS as a Leader in the Forrester Wave: Serverless Development Platforms, Q2 2025.

Forrester does not endorse any company, product, brand, or service included in its research publications and does not advise any person to select the products or services of any company or brand based on the ratings included in such publications. Information is based on the best available resources. Opinions reflect judgment at the time and are subject to change. For more information, read about Forrester’s objectivity here .

Introducing AWS Lambda native support for Avro and Protobuf formatted Apache Kafka events

Post Syndicated from Julian Wood original https://aws.amazon.com/blogs/compute/introducing-aws-lambda-native-support-for-avro-and-protobuf-formatted-apache-kafka-events/

AWS Lambda now provides native support for Apache Avro and Protocol Buffers (Protobuf) formatted events with Apache Kafka event source mapping (ESM) when using Provisioned Mode. The support allows you to validate your schema with popular schema registries. This allows you to use and filter the more efficient binary event formats and share data using schema in a centralized and consistent way. This blog post shows how you can use Lambda to process Avro and Protobuf formatted events from Kafka topics using schema registry integration.

This new capability works with both Amazon Managed Streaming for Apache Kafka (Amazon MSK), Confluent Cloud and self-managed Kafka clusters. To get started, update your existing Kafka ESM to Provisioned Mode and add schema registry configuration, or create a new ESM in Provisioned Mode with schema registry integration enabled.

Avro and Protobuf

Many organizations use Avro and Protobuf formats with Apache Kafka because these binary serialization formats offer advantages over JSON. They provide 50-80% smaller message sizes, faster serialization and deserialization performance, robust schema evolution capabilities, and strong typing across multiple programming languages.Working with these formats in Lambda functions previously necessitated custom code. Developers needed to implement schema registry clients, handle authentication and caching, write format-specific deserialization logic, and manage schema evolution scenarios.

What’s new

Lambda’s Kafka Event Source Mapping (ESM) now provides built-in integration with AWS Glue Schema Registry, Confluent Cloud Schema Registry, and self-managed Confluent Schema Registry. When you configure schema registry settings for your Kafka ESM, the service automatically validates incoming JSON Schema, Avro, and Protobuf records against their registered schema. This moves complex schema registry integration logic from your application layer to the managed Lambda service.

You can build your function with Kafka’s open-source ConsumerRecords interface using Powertools for AWS Lambda to get your Avro or Protobuf generated business objects directly. Optionally you can specify to get your records in the JSON format, where your function receives clean, validated JSON data regardless of the original serialization format, removing the need for custom deserialization code in your Lambda functions. This also allows you to create Kafka consumers across multiple programming languages.

Powertools for AWS Lambda is a developer toolkit that provides specific support for Java, .NET, Python, and TypeScript, maintaining consistency with existing Kafka development patterns. You can directly access business objects without custom deserialization code.

You can also setup filtering rules to discard irrelevant, JSON, Avro or Protobuf formatted events before function invocations, which can improve processing performance and reduce costs.

How schema validation works

When you configure schema registry integration for your Kafka ESM, you specify the registry endpoint, authentication details, and which event fields (key, value, or both) to validate. The ESM polls your Kafka topics for records as usual but now performs additional processing before invoking your Lambda function.For each incoming event, the ESM extracts the schema ID embedded in the serialized data. It fetches the corresponding schema from your configured registry. This process happens transparently, with schema definitions cached for up to 24 hours to optimize performance. The ESM identifies the format of your events using schema metadata and validates the event structure. It keeps either the original binary data or deserializes it to JSON format based on your customer configuration and sends it to your function for processing.


Figure 1: Kafka processing flow diagram.

The ESM handles schema evolution automatically. When producers begin using new schema versions, the service detects the updated schema IDs and fetches the latest definitions from your registry. This makes sure that your functions always receive properly deserialized data without requiring code changes.

Event record format

As a part of the ESM schema registry configuration, you need to specify Event Record Format, which Lambda uses to deliver validated records to your function. The schema registry configuration supports SOURCE and JSON.

SOURCE preserves the original binary format of the data as a base64-encoded string with producer-appended schema-id removed. This allows direct conversion to Avro or Protobuf objects so that you can use Kafka’s ConsumerRecords interface for a Kafka-like experience. Use this format when working with strongly typed languages or when you need to maintain the full capabilities of Avro or Protobuf schemas. Then, you can use any Avro or Protobuf deserializer to convert raw bytes to your business object. Powertools provides native support for this deserialization.

With JSON, the ESM deserializes the data ready for direct use in languages with native JSON support. Use this when you don’t need to preserve the original binary format or work with generated classes. You can also use Powertools to convert the base64 to your business object. See the documentation for payload formats and deserialization behavior.

If you configure filtering rules, then they operate on the JSON-formatted events after deserialization. This upstream filtering prevents unnecessary Lambda invocations for events that don’t match your processing criteria, directly reducing your compute costs.

Configuration and setup

To use this feature, you must enable Provisioned Mode for your Kafka ESM, which provides the dedicated compute resources needed for schema registry integration.

You can configure the integration through the AWS Management Console, AWS Command Line Interface (AWS CLI), AWS Language SDKs, or infrastructure as code (IaC) tools such as the AWS Serverless Application Model (AWS SAM) or AWS Cloud Development Kit (AWS CDK).

Your schema registry configuration includes the registry endpoint URL, authentication method (AWS Identity and Access Management (IAM) for AWS Glue Schema Registry, or Basic Auth, SASL/SCRAM, or mTLS for Confluent registries), and validation settings. You specify which event attributes to validate and optionally define filtering rules using standard Lambda event filtering syntax.

For error handling, configure Lambda failure destinations where events that fail schema validation or deserialization are sent. This makes sure that problematic events don’t disappear silently but are routed to other services such as Amazon Simple Queue Service (Amazon SQS), Amazon Simple Notification Service (Amazon SNS), and Amazon S3 for debugging and analysis.

Seeing the new features in action

There are a number of Serverless Patterns that you can use to process Kafka streams using Lambda. This example uses the Java pattern.

Deploy a sample Amazon MSK cluster

To set up an Amazon MSK cluster, follow the instructions in the GitHub repo and create a new AWS CloudFormation stack using the MSKAndKafkaClientEC2.yaml template file. The stack creates the Amazon MSK cluster, along with a client Amazon EC2 instance, to manage the Kafka cluster. There are costs involved when running this infrastructure.

  1. Connect to the EC2 instance using EC2 Instance Connect.
  2. Check that the Kafka topic is created by checking the contents of the kafka_topic_creator_output.txt file.
    cat kafka_topic_creator_output.txt

  3. The file should contain the text: “Created topic MskIamJavaLambdaTopic.”

Deploy the Glue schema registry and consumer Lambda function

The EC2 instance contains the software needed to deploy the schema registry and Lambda function.

  1. Change directory to the pattern directory.
    cd serverless-patterns/msk-lambda-iam-java-sam
  2. Build the application using AWS SAM.
    sam build
  3. To deploy your application for the first time, run the following in the EC2 instance shell:
    sam deploy --capabilities CAPABILITY_IAM --no-confirm-changeset \
    	--no-disable-rollback --region $AWS_REGION --stack-name msk-lambda-schema-avro-java-sam --guided

  4. You can accept all the defaults by hitting Enter. You can browse to the AWS Glue schema registry console and view the ContactSchema definition:
    {
      "type": "record",
      "name": "Contact",
      "fields": [
        {"name": "firstname", "type": "string"},
        {"name": "lastname", "type": "string"},
        {"name": "company", "type": "string"},
        {"name": "street", "type": "string"},
        {"name": "city", "type": "string"},
        {"name": "county", "type": "string"},
        {"name": "state", "type": "string"},
        {"name": "zip", "type": "string"},
        {"name": "homePhone", "type": "string"},
        {"name": "cellPhone", "type": "string"},
        {"name": "email", "type": "string"},
        {"name": "website", "type": "string"}
      ]
    }
    

    The consumer Lambda function ESM is configured for Provisioned Mode.

  5. View the ESM configuration from the Lambda console for the Lambda function name prefixed with msk-lambda-schema-avro-ja-LambdaMSKConsumer.
  6. Choose the MSK Lambda trigger which opens the Triggers pane under Configuration.
    Figure 2: View Lambda ESM schema configuration
  7. The configuration specifies using the Event record format SOURCE so your function can use Kafka’s native open-source ConsumerRecords interface. Powertools then deserializes the payload.
  8. The schema validation attribute is VALUE.
  9. The ESM filter configuration only processes the records that match zip codes of 2000.
  10. In your function code, specify the open-source Kafka ConsumersRecords interface by including Powertools for Lambda as a dependency. ConsumerRecords provides metadata about Kafka records and allows you to get direct access to your Avro/Protobuf generated business objects without requiring any additional deserialization code.
package com.amazonaws.services.lambda.samples.events.msk;

import com.amazonaws.services.lambda.runtime.Context;
import com.amazonaws.services.lambda.runtime.RequestHandler;
import org.apache.kafka.clients.consumer.ConsumerRecord;
import org.apache.kafka.clients.consumer.ConsumerRecords;
import org.slf4j.Logger;
import org.slf4j.LoggerFactory;
import software.amazon.lambda.powertools.kafka.Deserialization;
import software.amazon.lambda.powertools.kafka.DeserializationType;
import software.amazon.lambda.powertools.logging.Logging;

public class AvroKafkaHandler implements RequestHandler<ConsumerRecords<String, Contact>, String> {
    private static final Logger LOGGER = LoggerFactory.getLogger(AvroKafkaHandler.class);

    @Override
    @Logging(logEvent = true)
    @Deserialization(type = DeserializationType.KAFKA_AVRO)
    public String handleRequest(ConsumerRecords<String, Contact> records, Context context) {
        LOGGER.info("=== AvroKafkaHandler called ===");
        LOGGER.info("Event object: {}", records);
        LOGGER.info("Number of records: {}", records.count());
        
        for (ConsumerRecord<String, Contact> record : records) {
            LOGGER.info("Processing record - Topic: {}, Partition: {}, Offset: {}", 
                       record.topic(), record.partition(), record.offset());
            LOGGER.info("Record key: {}", record.key());
            LOGGER.info("Record value: {}", record.value());
            
            if (record.value() != null) {
                Contact contact = record.value();
                LOGGER.info("Contact details - firstName: {}, zip: {}", 
                           contact.getFirstname(), contact.getZip());
            }
        }
        
        LOGGER.info("=== AvroKafkaHandler completed ===");
        return "OK";
    }
}
Produce and consumer records

To send messages to Kafka, there is a LambdaMSKProducerJava function.

  1. Invoke the function from the Lambda console or CLI within the EC2 instance.
    sam remote invoke LambdaMSKProducerJavaFunction --region $AWS_REGION \
    	--stack-name msk-lambda-schema-avro-java-sam

  2. You can view the Producer logs to see the 10 records produced.The consumer Lambda function processes the records.
  3. View the consumer Lambda function logs using the Amazon CloudWatch logs console or CLI within the EC2 instance.
    sam logs --name LambdaMSKConsumerJavaFunction \
    	--stack-name msk-lambda-schema-avro-java-sam --region $AWS_REGION

The Lambda function processes and logs only the records that match the filter FILTER. The Avro binary data is deserialized using Powertools for AWS Lambda. You should see the function logs showing each record processed with the decoded keys and values.


Figure 3: Lambda consumer logs showing Avro processing

Cleaning up

You can clean up the example Lambda function by running the sam delete command.

sam delete

If you created the Amazon MSK cluster and EC2 client instance, then navigate to the CloudFormation console, choose the stack, and choose Delete.

Performance and cost considerations

Schema validation and deserialization can add processing time before your function invocation. However, this overhead is typically minimal when compared to the benefits. ESM caching minimizes schema registry API calls. Using filtering allows you to reduce costs, depending on how effectively your filtering rules eliminate irrelevant events. This feature simplifies the operational overhead of managing schema registry integration code so teams can focus on business logic rather than infrastructure concerns.

Error handling and monitoring

If schema registries become temporarily unavailable, then cached schemas allow event processing to continue until the registry is available again. Authentication failures generate error messages with automatic retry logic. Schema evolution happens seamlessly as Lambda automatically detects and fetches new versions.

If events fail validation or deserialization, they are routed to your configured failure destinations. For Amazon SQS and Amazon SNS destinations, the service sends metadata about the failure. For Amazon S3 destinations, both metadata and the original serialized payload are included for detailed analysis.

You can use standard Lambda monitoring, with more CloudWatch metrics providing visibility into schema validation success rates, registry API usage, and filtering effectiveness.

Conclusion

AWS Lambda now supports Avro and Protobuf formats for Kafka event processing in Provisioned Mode for Kafka ESM. This enables schema validation, event filtering, and integration with both Amazon MSK, Confluent, and self-managed Kafka clusters. Whether you’re building new Kafka applications or migrating existing consumers to Lambda, this native schema registry integration streamlines processing pipelines.

For more information about the Lambda Kafka integration capabilities, go to the learning guide, Lambda ESM documentation. To learn about Lambda pricing, such as Provisioned Mode costs, visit the Lambda pricing page.

For more serverless learning resources, visit Serverless Land.

How Stellantis streamlines floating license management with serverless orchestration on AWS

Post Syndicated from Göksel SARIKAYA original https://aws.amazon.com/blogs/architecture/how-stellantis-streamlines-floating-license-management-with-serverless-orchestration-on-aws/

This post is written by Goeksel Sarikaya, Senior Delivery Consultant at AWS, and Milosz Stawarski, Senior Software Architect at Stellantis.

Software licensing is a critical aspect of many organizations’ operations, with various models available to suit different needs. Two common types are named user licenses, which are assigned to specific individuals, and floating licenses, which can be shared among a pool of users. Some independent software vendors (ISVs) offer both options, whereas others might have limitations, particularly in cloud environments.

In this post, we explore a unique scenario where an ISV, unable to provide a floating license option for cloud usage, worked with Stellantis to develop an alternative solution. This approach, implemented with the ISV’s permission, treats named user licenses as if they were floating, automatically assigning and removing them based on the state of user workbench instances.

This solution is not intended to circumvent licensing terms or reduce costs at the expense of ISVs. Rather, it’s a collaborative approach to address specific customer needs when traditional floating licenses aren’t available. We will demonstrate how the solution uses serverless AWS services like Amazon EventBridge, AWS Lambda, Amazon DynamoDB, and AWS Systems Manager, keeping in mind that any similar implementation should only be pursued with explicit permission from the software vendor.

Overview of Stellantis

Stellantis N.V., born from the merger of FCA and PSA Group, leads the change towards software defined vehicles (SDV). As part of this transformation, AWS and Stellantis created the Virtual Engineering Workbench (VEW), a modular framework to develop, integrate, and test vehicle software in the cloud, ultimately connecting their vehicles to the cloud.

The VEW provides predefined environments tailored to specific use cases. These environments come fully equipped with the tools, integrated development environments (IDEs), and licensing necessary for developers to jumpstart their projects.

For more details on VEW, refer to Stellantis’ SDV transformation with the Virtual Engineering Workbench on AWS.

Overview of solution

As the number of developers and projects grew, Stellantis faced a challenge in managing the limited number of named user licenses for their software tools. The manual process of assigning and revoking licenses became increasingly time-consuming and inefficient, potentially hindering the agility and productivity of their development teams.

Stellantis and AWS tackled this challenge head-on by collaborating on an innovative, dynamic license management solution using AWS serverless services. This solution transforms the traditional named user license model into a more flexible floating license system, automatically assigning and revoking licenses based on the state of user workbench instances. The licenses and solution discussed in this post pertain solely to the use of standalone software tools such as those used in automotive domains. These do not involve sharing of user data or content when licenses are reused.

Before we dive into the detailed workflow of the solution, let’s examine the high-level architecture. The following diagram illustrates how various AWS services work together to create this efficient license management system.

Multi-region AWS license management architecture showing event-driven workflows between toolchain and user accounts with VEW workbench integration

Architecture

This architecture uses key AWS services such as EventBridge, Lambda, DynamoDB, and Systems Manager to create a scalable, serverless solution that significantly reduces administrative overhead and optimizes license utilization.

In the following sections, we explore each component of this architecture in detail, explaining how they interact to provide a seamless license management experience for Stellantis’ VEW.

In workbench accounts (user accounts)

The design is serverless and based on an event-driven approach. The workflow in the user accounts is as follows:

  1. Workbench instances are Amazon Elastic Compute Cloud (Amazon EC2). Their start and stop automatically sends AWS events.
  2. An EventBridge rule invokes a Lambda function when such an event occurs. This function checks the tags on the EC2 instance to distinguish workbenches from other EC2 instances. Two tags are important for identifying workbench instances: vew:workbench:ownerId and vew:workbench:type.
  3. The Lambda function creates a custom event with the following data: user-id, workbench-type, workbench-state, and instance-id, and sends this event to the default event bus.
  4. An EventBridge rule forwards the custom event to a custom event bus in the license server account.

In license server account

The following steps take place in the license server account:

  1. An EventBridge rule invokes a Lambda
  2. This function interacts with a DynamoDB table that stores a mapping of licensed products to users. The function does the following:
    1. Deduces the licensed products present in the workbench from the workbench type.
    2. For each licensed product, it verifies if the combination of product and user is already present in the DynamoDB
    3. If the workbench is starting:
      1. If the combination is already present, it increases the count of workbenches in the table for this item by 1.
      2. If the combination is not present, it creates a new item in the table (product, user-id, workbench-count, timestamp).
    4. If the workbench is stopping, it decreases the count of workbenches in the table for this item by 1. If the count becomes 0, the item is deleted.
  3. Any update to the DynamoDB table triggers another Lambda
  4. If the change in the table is a creation of a new entry or deletion of an entry, this function writes the current timestamp to a Systems Manager parameter in both cases. This is so that if no changes are detected in the database, we don’t unnecessarily run the xLC (License Client for related product) caller function.
  5. Another Lambda function is invoked every minute. It compares the timestamp written in the Systems Manager parameter indicating a DynamoDB item creation or deletion with the last time the function called the xLC CLI to assign users to a license.
  6. If the DynamoDB timestamp is earlier, the function stops. If the DynamoDB timestamp is later, the function queries the table for obtaining the user-id for each product.
  7. To maintain a comprehensive record of license assignment operations, you can enable data plane events for DynamoDB in AWS CloudTrail.
  8. For each licensed product, the function uses Run Command, a capability of Systems Manager, to invoke the xLC CLI API on the license server to assign named users to a license for a product. The function provides the list of users assigned to the product to the API. This updates the named user list on the license server—the list is completely overwritten, which includes adding new user IDs and removing ones that are no longer needed.

Benefits and key features

The solution offers the following benefits:

  • Automated license assignment and removal – Users are automatically assigned licenses when their workbench instances start, and licenses are returned to the pool when instances stop, providing efficient license utilization.
  • Scalable and serverless architecture – The solution is built on serverless AWS services, allowing it to scale seamlessly as the number of users and workbench instances grows, without the need for provisioning or managing servers.
  • Centralized license management – The license server account acts as a central hub for managing licenses across multiple workbench accounts, simplifying administration and providing a unified view of license usage.
  • Reduced administrative overhead – By automating the license assignment and removal process, the solution can significantly reduce the administrative burden associated with manual license management.
  • Optimized license utilization – Licenses are assigned only when needed and returned to the pool when no longer required, maximizing license availability and minimizing idle licenses.
  • Monitoring and metrics – The solution provides monitoring capabilities and license usage metrics, enabling better visibility and informed decision-making regarding license procurement and allocation.

Conclusion

By implementing this serverless solution, it is possible to transform a manual named user license management systems to an automated floating license system for software tools. The event-driven architecture and serverless components provide efficient and scalable license assignment and removal based on the workbench instance state.

This solution has streamlined the license management process, reducing administrative overhead and optimizing license utilization. It is now possible to provision software tools more efficiently, improving productivity and resource allocation across the organization. Additionally, the centralized license management and monitoring capabilities provide better visibility and control over license usage, enabling informed decision-making and cost optimization.

Overall, this AWS based floating license solution has empowered organizations to use software tools more effectively, while minimizing the operational burden associated with license management. For more serverless learning resources, visit Serverless Land.


About the authors

Dynamically routing requests with Amazon API Gateway routing rules

Post Syndicated from Anton Aleksandrov original https://aws.amazon.com/blogs/compute/dynamically-routing-requests-with-amazon-api-gateway-routing-rules/

Effective API management and routing capabilities are crucial for organizations managing complex application architectures. Whether you’re a technology company rolling out new API versions to millions of users, or a financial services organization conducting A/B tests to optimize customer experiences, the ability to route API traffic dynamically and efficiently is essential.

Today, Amazon API Gateway announces support for dynamic routing rules for custom domain names in all supported AWS Regions. This new capability enables you to route API requests based on HTTP header values, either independently or in combination with URL paths. In this post, you will learn how to use this new capability to implement routing strategies such as API versioning and gradual rollouts without modifying your API endpoints.

Dynamic Routing Rules Overview

Many organizations require dynamic API routing capabilities to support their evolving business needs. As a line-of-business persona, you want to be able to test new user experiences with specific customer segments, while maintaining their existing flows intact. As an engineer, you want to be able to maintain multiple API versions across different client applications while ensuring regulatory compliance. Prior to this launch, developers using API Gateway implemented dynamic routing by using different URL paths, such as “/v1/products” and “/v2/products”.

With this new launch, you can implement dynamic routing logic with a simple declarative configuration within the custom domain name settings. The new routing rule mechanism allows you to make routing decisions based on HTTP headers, base paths, or a combination of both. Developers are no longer required to create new or alter existing paths to smoothly transition between API versions, they can simply specify the desired value in the request HTTP header. Among other possibilities, you can implement cell-based architecture routing, A/B testing, or dynamic backend selection based on hostname, tenant ID, accepted response media type, or cookie value. By implementing routing logic directly within the API Gateway, you can eliminate proxy layers and complex URL structures while maintaining fine-grained control over your API traffic. This new feature seamlessly integrates with existing API Gateway capabilities and supports both public and private REST APIs. The following diagram shows how you can use routing rules for header and base-path based routing. This example uses a single level resource /products to show path matching, however depending on your use-case you could also use multi-level paths like /products/items.

Figure 1. Using routing rules for header and base-path based routing

In the following section you’ll learn how to implement header-based routing, use the new routing rules construct for common scenarios like API versioning and A/B testing, and configure rules with different routing conditions and priorities to achieve the desired behavior.

What is a routing rule

A routing rule is a new resource type uniquely associated with a single custom domain. It represents a collection of conditions that, when matched, cause the incoming request to be forwarded to a specific API and stage. Routing rules have three configuration properties:

  • The Conditions property defines the criteria that must be met for actions to be taken. A rule can include up to two header conditions and one base path condition, and all specified conditions must be met to trigger the action. If no conditions are defined for a rule, it serves as a catch-all rule matching all requests.
  • The Actions property defines what actions will be taken when rule conditions are met. At the time of this launch the supported action is invoking any stage of any REST API within the same account and region boundaries.
  • The Priority property defines the order that rules are evaluated in, with 1 being highest priority and 1,000,000 the lowest. You cannot reuse same priority value for more than one rule. AWS recommends you leave ample space between sequential rules to make it easy to add new rules in future, for example use 100, 200, 300 instead of 1, 2, 3.

Header conditions, specified via a MatchHeaders property, are used to match HTTP request header values, such as x-version=v1. Conforming to RFC 7230, header names are not case sensitive, while header values are. You can also use wildcards in header values for prefix, suffix, and contains match. See the following examples using AWS CloudFormation templates:

Exact match:

- MatchHeaders: 
	AnyOf: 
		- Header: "x-version" 
		ValueGlob: "alpha-v2-latest"

Will only match x-version=alpha-v2-latest

Prefix match:

- MatchHeaders: 
	AnyOf: 
	- Header: "x-version" 
	ValueGlob: "*latest"

Matches x-version=alpha-v2-latest, but not x-version=alpha-v2

Suffix match:

- MatchHeaders: 
	AnyOf: 
		- Header: "x-version" 
		ValueGlob: "alpha*"

Will match x-version=alpha-v2-latest and x-version=alpha-v1, but not x-version=beta-v1

Prefix and suffix match.

- MatchHeaders: 
	AnyOf: 
		- Header: "x-version" 
		ValueGlob: "*v2*"

Matches x-version=alpha-v2-latest and x-version=beta-v2-test, but not x-version=alpha-v1

Base path condition, specified via MatchBasePaths property, is used to match the incoming request path. The matching is case sensitive.

- MatchBasePaths: 
	AnyOf: 
		- "products"

You can have up to two MatchHeaders and one MatchBasePaths conditions per routing rule. Conditions are evaluated using the AND operator, meaning all conditions must be met for the action to be taken. Both condition types support a single comparison value under AnyOf property. The following snippet illustrates a sample routing rule with two MatchHeaders conditions and a single MatchBasePaths condition.

ProductsV1RoutingRule: 
	Type: 'AWS::ApiGatewayV2::RoutingRule' 
	Properties: 
		DomainNameArn: !Sub "arn:aws:apigateway:${AWS::Region}::/domainnames/${ApiCustomDomain}" 
		Priority: 100 
		Conditions: 
			- MatchHeaders: 
				AnyOf: 
					- Header: "x-version" 
					ValueGlob: "v2" 
			- MatchHeaders: 
				AnyOf: 
					- Header: "x-user-cohort" 
					ValueGlob: "beta-testers" 
			- MatchBasePaths: 
				AnyOf: 
					- "products" 
		Actions: 
				- InvokeApi:
					ApiId: !Ref ProductsV2Api 
					Stage: !Ref ProductsV2Stage

This rule matches requests to https://example.com/products when both header conditions are met – x-version=v2 and x-user-cohort=beta-testers. This rule does not match requests to any other base path, such as https://example.com/orders, or requests that do not match at least one header condition.

For scenarios like API versioning, you can create rules that evaluate headers such as “accept” or “version” to route traffic to different API implementations. For example, to route requests containing “x-version: api-beta” to your beta API, you would create a rule specifying this header condition and set the action to route to your beta API deployment.

Header-based routing also simplifies A/B testing by allowing you to define client cohorts based on custom headers, allowing controlled experiments with different configurations. You can create rules that check for a custom header like “x-test-group” to route specific users to different API implementations. The priority system ensures predictable routing behavior – when multiple rules match a request, the rule with the lowest priority number (highest precedence) determines the routing. Combining header and path conditions within a single rule enables complex routing scenarios such as version-specific routing for specific API resources instead of the entire API, as illustrated in the following diagram.

Figure 2. A routing configuration with two header and one path conditions in API Gateway Console.

Review the API Gateway documentation for detailed guide on creating routing rules.

Configuring Routing Mode

Before you begin creating routing rules, you must first create at least one API, stage, and a custom domain name. You can configure your custom domain name with the new routing mode setting.

  • API mappings only. This is the default mode. When using this mode, you can continue to use base path mappings to route requests to different APIs, and not use Routing Rules at all. This mode maintains the current behavior, where requests are routed based on base path mappings only.
  • Routing rules then API mappings. With this mode you can use Routing Rules while continuing to keep base path mappings as a fallback. When you use this mode, the Routing Rules always take precedence, and unmatched requests are evaluated against base path mappings. This mode is useful for gradually transitioning your APIs to Routing Rules.
  • Routing rules only. This mode gives you the flexibility to use routing rules only, and not rely on the base paths that you may have previously created on the domain using API mappings. This is the recommended routing mode; it is helpful when you are starting off with a new custom domain or finished transitioning from API mappings to Routing Rules for an existing custom domain.

When switching from one routing mode to another, always test your new configuration in non-production environments first. For example, when switching mode from API mappings only to routing rules only, your traffic will only be routed with routing rules; existing API mappings will no longer take effect.

Onboarding to Header-Based Routing

You can adopt the new Header-Based Routing for your existing API Gateway custom domains with zero-downtime, risk-minimized approach. The first step is to configure your custom domain to use the Routing rules then API mappings mode using the API Gateway console, AWS CLI, or your infrastructure-as-code (IaC) tool. This configuration ensures that while you gradually create Routing Rules, your existing base path mappings continue to function as fallback routes. Since Routing Rules are evaluated before base path mappings, and in the absence of any matching rules, requests automatically fall back to your existing base path mappings, your current API traffic remains unaffected during this transition.

Once you’ve configured the routing mode, you can progressively introduce Routing Rules alongside your existing setup. For example, you might start by creating a rule with a specific test header that routes to a new API version, allowing you to validate the routing behavior with controlled test traffic while production traffic continues flowing through your existing base path mappings. As you gain confidence in the new routing configuration, you can gradually expand your rules, adjust priorities, and optionally migrate away from base path mappings entirely. This incremental approach, combined with API Gateway’s observability capabilities described in the next section, enables you to validate each change and ensure your API consumers experience no disruption during the transition.

Observability

API Gateway provides comprehensive visibility into how your routing rules are processing requests through access logging. Each request now includes additional context variables that help you understand the routing decision process. The $context.customDomain.routingRuleIdMatched variable identifies which rule was matched and applied to the request, while existing variables like $context.domainName, $context.apiId, and $context.stage provide the complete routing context. By analyzing these access logs, you can verify routing behavior, troubleshoot unexpected routes, and gather insights about traffic patterns across different API versions or test variants.

End-to-end example

Consider a real-world scenario where a team needs to gradually migrate users to a new API version, such as an e-commerce platform updating its checkout API from v1 to v2. First, the team creates two different REST APIs – one for each version. Then, they set up a Routing Rule with priority 100 that checks for the header x-version=v2 and routes matching requests to the v2 API. They also create another rule with priority 200 that routes all requests with paths starting with /checkout to v1 API as a fallback.

Figure 3. Gradually transitioning clients from v1 to v2 API.

In the application code they add the x-version header for a small percentage of users. They monitor the performance and error rates using API Gateway’s telemetry capabilities by tracking the access and execution logs, along with emitted metrics. As their confidence grows, they gradually increase the percentage of users sending the v2 header. This approach ensures a controlled migration with minimal risk and ability to quickly rollback by simply removing the header from requests or changing a routing rule.

Sample

Follow the instructions in this GitHub repository to provision the sample in your AWS account. The project illustrates using dynamic routing with API Gateway.

Conclusion

Header-based routing brings significant advantages to API Gateway users. The feature’s backward compatibility ensures a smooth transition path – you can maintain existing base path mappings while gradually adopting Routing Rules, or use both mechanisms simultaneously with the fallback option. This flexibility allows you to migrate at your own pace without disrupting existing applications. The solution is cost-effective, with no additional charges for using Routing Rules on REST APIs. It reduces requirements to leverage extra service and infrastructure for dynamic routing. The priority-based evaluation system provides deterministic routing behavior, making it easier to understand and troubleshoot routing decisions.

To learn more about API Gateway header-based routing see the service documentation.

To learn more about Serverless architectures see Serverless Land.

Powering global payout intelligence: How MassPay uses Amazon Redshift Serverless and zero-ETL to drive deeper analytics.

Post Syndicated from Yossi Shlomo original https://aws.amazon.com/blogs/big-data/powering-global-payout-intelligence-how-masspay-uses-amazon-redshift-serverless-and-zero-etl-to-drive-deeper-analytics/

Since the company was founded in 2019, MassPay’s singular objective has been to deliver frictionless global payments that power innovation and lift people, businesses, and quality of life worldwide. Today, the MassPay payment orchestration offering empowers companies to move money across borders effortlessly; enabling local payment experiences in over 175 countries and 70 currencies—including digital wallets, locally preferred alternative payment methods, and cryptocurrencies. From hyper-localized checkout experiences to instant global payouts, we orchestrate seamless financial experiences that reflect how people and businesses transact around the world.

As we have expanded globally, so has the complexity of our data. In this blog post we shall cover how understanding real-time payout performance, identifying customer behavior patterns across regions, and optimizing internal operations required more than traditional business intelligence and analytics tools. And how since implementing Amazon Redshift and Zero-ETL, we’ve seen 90% reduction in data availability latency, payments data available for analytics 1.5x faster, leading to 45% reduction in time-to-insight and 37% fewer support tickets related to transaction visibility and payment inquiries.

Unlocking deeper payout intelligence and global insights

To continue our innovation—and to continue to exceed our partners’ and customers’ expectations—we knew we needed to go beyond basic reporting. We know success is dependent upon developing a truly data-driven organization. This means tracking granular KPIs across payout success rates, payment method adoption, transaction velocity, customer onboarding funnel drop-off, and support ticket correlation. We also wanted to better forecast customer payment expectations, monitor foreign exchange cost trends, and understand market-specific nuances such as how payout timing impacts seller satisfaction in social commerce ecosystems.

“We didn’t just want more data. We wanted faster, smarter insights that would shape decisions in real time. Being a data-driven organization means our teams don’t guess. They know. And that gives us, our partners, and our customers real operational and competitive advantages.”

– Yossi Schlomo, Director of Payment Systems Architecture

MySQL databases, CSV exports, and third-party reporting tools wouldn’t support the scale or speed we needed to deliver.

Choosing AWS: A scalable and integrated analytics foundation

We chose Amazon Web Services (AWS) for our data infrastructure and to accelerate our analytics capabilities.

At the core of our stack is Amazon Redshift Serverless with AI-driven scaling and optimizations enabled, which gives us scalable, fast, and cost-efficient analytics without the burden of managing infrastructure. Coupled with Amazon Aurora MySQL-Compatible Edition as our transactional data store and Amazon Redshift zero-ETL integration, we eliminated manual data pipelines altogether. Transactional data flows into Amazon Redshift in near real-time, instantly powering dashboards, alerts, and machine learning (ML) models.

This data feeds interactive dashboards—both internally and embedded within our platform for customers. Now, executives, operations leads, and customer success teams can drill into payout performance by region, merchant, or payment method, while customers get real-time visibility into their own payout analytics as part of our platform experience. The architecture is shown in the following figure.

MassPay Zero-ETL architecture with Amazon Redshift Serverless

MassPay Zero-ETL architecture with Amazon Redshift Serverless

Why it’s different and what it unlocked

Without Amazon Redshift Serverless and zero-ETL, we would have had to invest in costly custom data pipelines, maintain separate exchange, transform, and load (ETL) infrastructure, and manually manage data freshness. The integration with Aurora MySQL-Compatible is seamless and reduces our analytics latency from minutes to seconds.

“Our differentiator is simple: We operationalize not just transactions but analytics for global payments. Most platforms can tell you if a transaction went through. For payments and payouts, MassPay can tell you how fast it went, what it cost, what method was most effective, and what that means for your business in real time.”

– Yossi Schlomo, Director of Payment Systems Architecture

Embedded intelligence, built for scale

Every MassPay customer gets access to comprehensive payment analytics. These are accessed using our API or through a white-label dashboard (shown in the following figure). This detail is core to our product and central to our value proposition. As part of our go-to-market strategy, we showcase these capabilities in every demo, and they’ve proven to be key drivers in conversion and upsell conversations, especially with platforms targeting high-growth ecosystems.We use tiered pricing models based on transaction volume, and our embedded intelligence helps our partners and customers optimize usage and scale efficiently.

MassPay Dashboard

MassPay Dashboard

What we’ve gained

Since implementing Amazon Redshift and Zero-ETL, we’ve seen measurable results including:

  • 90% reduction in data availability latency and data available for analytics 1.5x faster
  • 45% reduction in time-to-insight across payment and payout intelligence reports
  • 37% fewer support tickets related to transaction visibility and payment inquiries
  • Real-time Net Promoter Score (NPS) tracking correlates with payout success metrics, driving faster resolution paths

What’s next

We’re now extending our analytics model to include more advanced ML-based payout failure prediction and ML-based payment authorization prediction, FX optimization alerts, partner-level and network-level benchmarking, and much more.

Conclusion

MassPay isn’t just payments. We aren’t just payouts. We are the engine powering modern commerce. With AWS, we’re turning complex global payments infrastructure into a smart, transparent, and scalable platform for insights. For our partners, and for our customers, this means better decisions, faster payment processing, faster payouts, and truly global reach without guesswork.

We encourage you to leverage below resources to explore these features further


About the authors

Yossi Shlomo serves as the Director of Payment Systems Architecture at MassPay. Yossi is an expert in credit card payment systems, PCI compliance, and secure transaction architecture, helping global platforms process payments at scale with confidence. He specializes in building scalable, cloud-based transaction systems and optimizing global payment gateways for performance and reliability.

Milind Oke is a Amazon Redshift and SageMaker Lakehouse specialist Solutions Architect as AWS. He is based out of New York and has been building enterprise data platforms, data warehousing, and analytics solutions for customers across various domains over two decades. In the 5 years with AWS, Milind has been a speaker at worldwide technical conferences and is co-author of Amazon Redshift: The Definitive Guide: Jump-Start Analytics Using Cloud Data Warehousing 1st Edition.

How Launchpad from Pega enables secure SaaS extensibility with AWS Lambda

Post Syndicated from Anton Aleksandrov original https://aws.amazon.com/blogs/architecture/how-launchpad-from-pega-enables-secure-saas-extensibility-with-aws-lambda/

Large organizations increasingly adopt software as a service (SaaS) solutions to focus on business priorities, reduce infrastructure management overhead, and optimize costs. These organizations expect SaaS vendors to provide customizability facilities for tailoring the solution behavior according to their needs. Although traditional approaches like feature flags and webhooks offer some flexibility, they often fall short of providing a high degree of customizability. A new emerging pattern in this space is tenant-supplied custom code execution, which allows tenants to inject their own code into specific workflow points, enabling deep customization while preserving the core SaaS solutions’ integrity and security.

In this post, we share how Pegasystems (Pega) built Launchpad, its new SaaS development platform, to solve a core challenge in multi-tenant environments: enabling secure customer customization. By running tenant code in isolated environments with AWS Lambda, Launchpad offers its customers a secure, scalable foundation, eliminating the need for bespoke code customizations.

Solution overview

Launchpad, which is built on AWS, is an end-to-end platform on which software providers can build, launch, and operate workflow-centric B2B SaaS applications and AI solutions. It provides a managed, secure, scalable cloud environment for hosting multi-tenant applications and data. It accelerates the build experience with generative AI-powered low code tools, prebuilt capabilities, and subscriber-level configuration. Being a multi-tenant platform at its core, Launchpad had to maintain stringent isolation across tenants in its architecture.

One of the requirements Launchpad had was to allow their tenants to augment the workflows natively by providing custom code. Some common scenarios included communicating with external systems with proprietary non-industry-standard protocols, reuse of existing business logic, and SDK-based custom code development.

The solution necessitated the ability for tenants to provide custom code that would implement the required business logic, which Launchpad would be executing. This required architecting a secure runtime environment for custom code execution that maintains the highest degree of cross-tenant isolation within the multi-tenant architecture, at the same time allowing sufficient access to platform APIs and services. It was essential to build an architecture that would decouple the environment running tenant code from the core SaaS platform, as illustrated in the following diagram.

Architecting the solution topology

To achieve the required high level of compute isolation for running code provided by different tenants, Launchpad has adopted Lambda functions in its architecture as the secure ephemeral compute environment. Each untrusted code snippet provided by tenants is bootstrapped as a stand-alone Lambda function, with strong Firecracker-based isolation across different functions and execution environments addressing Launchpad’s requirements. This isolation provides dedicated resources, customizable access permissions, independent monitoring and operations, and automatic scaling for each function, while maintaining complete separation from other functions and their execution environments, as illustrated in the following diagram.

With Lambda being a serverless compute service, adopting it for the Launchpad architecture yielded several significant benefits. The major business benefit was that tenants could implement thousands of custom workflow augmentations on their own simply by providing code snippets, instead of the Launchpad engineering team being responsible for implementing them in the core platform code. Other benefits included:

  • Managed runtimes – AWS handles patching and updating the underlying infrastructure, operating system, and runtimes for customers, reducing the potential attack surface.
  • Fine-grained permissions – Each function can have its own set of access policies to tightly control what resources and actions it can access.
  • No need to pre-provision and pay for overprovisioned capacity – Lambda functions scale up and down automatically based on traffic patterns.
  • Built-in monitoring – Lambda functions emit detailed metrics, logs, and traces through Amazon CloudWatch and AWS X-Ray out of the box, making it straightforward to monitor tenant code execution.

To further reduce risks, Launchpad runs these Lambda functions with untrusted code in a dedicated AWS account. This account is separated from the core SaaS platform account. When end-users create a new function in the Launchpad authoring portal, they upload their code and specify the code handler to be executed during the invocation. Users can also map function input and output to Launchpad fields for further processing to enable an even higher degree of customizability and integration. The multi-tenant authoring service is a Control Plane component that runs as a microservice on the Amazon Elastic Kubernetes Service (Amazon EKS) cluster and uses the Lambda API for function lifecycle management, as illustrated in the following diagram. After a function resource is created, it can be used for further invocations.

Runtime architecture

At runtime, when Launchpad needs to invoke a function, it calls the Lambda Invoke API. Before the function is invoked, the multi-tenant runtime service performs a tenancy check to make sure the request is coming from an authorized tenant by doing the token validation. After a successful validation, the service invokes the required Lambda function. To invoke functions hosted in a different AWS account, the multi-tenant runtime service uses an AWS Identity and Access Management (IAM) role to assume the required permissions and invokes the Lambda service using the AWS SDK. The sequence of interactions is shown in the following architecture diagram.

The workflow consists of the following steps:

  1. An incoming user request reaches the application gateway service.
  2. The application gateway authenticates the request using the tenancy security service.
  3. After it’s authenticated, the request is forwarded to the multi-tenant runtime service
  4. The multi-tenant runtime service validates the supplied token and performs a tenancy check. This makes sure tenants can only invoke own functions they have permissions for (for example, functions they own).
  5. The multi-tenant runtime service pod assumes the IAM role required for invoking the tenant-specific Lambda function in a different AWS account.
  6. The multi-tenant runtime service pod invokes the required Lambda function.

Invoking the platform API from custom code is as straightforward as connecting to any external API. The custom code can authenticate with the platform using OAuth2. To facilitate the authentication, the developer can pass along the credentials as input parameters to the function from the core platform. Then the developer can create a corresponding record (isolated by tenant) in the platform that stores the credentials per function, and pass credentials as input parameters during invocation.

Distributed architecture observability

Operating a distributed architecture that runs untrusted code across multiple AWS accounts requires a comprehensive observability strategy. Launchpad’s approach combines centralized logging and monitoring with cross-account aggregation to provide a unified operational view of the platform.

The monitoring architecture uses CloudWatch Metrics to observe the Lambda functions, aggregating them through a centralized observability layer. This setup empowers platform operators to correlate Lambda function metrics with the core platform services running on Amazon EKS. Launchpad also collects per-function telemetry like function invocations, error rates, and execution time, which allows them to observe per-tenant metrics. These telemetry dimensions enable both a platform-wide and tenant-specific monitoring perspective.

For logging and troubleshooting, Launchpad implements a unified logging pipeline that aggregates Lambda function logs with application gateway and runtime service logs. Each request flowing through the system carries a correlation ID, so operators can trace execution paths across the core SaaS services and into the tenant functions running in the AWS account running tenant Lambda functions.

With this multi-layer observability architecture, Launchpad can maintain operational excellence while running tenant code securely at scale. Regular operational reviews drive continuous improvements in monitoring coverage and incident response procedures. Having per-tenant Lambda functions make it possible for Launchpad to use tenant-specific cost allocation tags, further empowering them to understand the cost footprint of running tenant custom code.

Best practices

When building a SaaS solution, maintaining a unified core code base is essential for scalability and manageability. Implementing per-tenant variations within the core platform code can lead to maintenance complexity and technical debt. Instead, architect your SaaS solution to have extension points, which allow your tenants to inject their custom code at specific points in the workflow, enabling customization without compromising the platform’s maintainability. This pattern makes sure the core SaaS platform remains clean and standardized while offering the flexibility that customers demand.

Additional best practices include:

  • Use separate accounts for running Lambda functions with untrusted tenant-provided code to make sure it’s isolated from your core SaaS platform code.
  • Grant absolute minimum required access permissions to the execution role assigned to the function. The custom code running within the execution environment gets permissions defined in the execution role when making requests to AWS API endpoints. If the function doesn’t need to reach out to AWS API endpoints, remove all permissions from the execution role and add an explicit AWSDenyAll policy.
  • Use separate Lambda functions for each code snippet and each tenant. This will provide the highest degree of cross-tenant isolation. Resources are not reused across different functions and execution environments.
  • Use Lambda layers in case you need to add a layer of vendor-provided code in order to keep it separated from the untrusted tenant-provided code.
  • Implement additional security controls, such as using Amazon Virtual Private Cloud (Amazon VPC) constructs to restrict network access and VPC Flow Logs for network activity monitoring.

Conclusion

The implementation of a secure untrusted code execution environment within SaaS platforms addresses a critical need for tenant customization while maintaining architectural integrity. Lambda offers a built-in isolation model, fine-grained security controls, and serverless scalability, so SaaS providers such as Launchpad can address the requirements of executing tenant-provided code in a multi-tenant environment and offer robust customization capabilities while maintaining strict security boundaries and operational efficiency. This architectural pattern enables providers to focus on core platform development while confidently supporting tenant-specific workflows through the secure and scalable Lambda execution environment.

To learn more, refer to the Security Overview of AWS Lambda white paper. For additional serverless architectural patterns, see Serverlessland.com.


About the authors

Introducing AWS Serverless MCP Server: AI-powered development for modern applications

Post Syndicated from Shridhar Pandey original https://aws.amazon.com/blogs/compute/introducing-aws-serverless-mcp-server-ai-powered-development-for-modern-applications/

Modern application development demands faster, more efficient ways to build and deploy software. Over the past decade, serverless computing has emerged as a transformative approach to software development, enabling developers to focus on building applications without having to manage the underlying infrastructure. As developers build their applications using AWS Serverless Compute, they seek guidance on selecting appropriate services, understanding best practices, and implementation patterns to make the most of this paradigm.

Today, AWS announces the open-source AWS Serverless Model Context Protocol (MCP) Server, a tool that combines the power of AI assistance with serverless expertise to enhance how developers build modern applications. The Serverless MCP Server provides contextual guidance specific to serverless development, helping developers make informed decisions about architecture, implementation, and deployment.

This post describes how the Serverless MCP Server works with AI coding assistants to streamline serverless development. Learn how to use this solution to accelerate your serverless development workflow and build robust, high-performing applications more efficiently.

Overview 

Serverless computing enables development teams to significantly reduce time-to-market while improving operational efficiency. Developers can focus on creating business value, while AWS services automatically handle scaling, availability, and infrastructure maintenance. AWS Lambda provides a seamless compute service where code runs in response to events, scaling instantly from a few requests per day to thousands per second. Through integration with over 200 AWS services, Lambda enables developers to build sophisticated applications using triggers from Amazon API Gateway, Amazon S3, Amazon DynamoDB, and many others. Whether you’re building data processing pipelines, real-time stream processing, or web applications, Lambda’s support for popular programming languages and development frameworks helps development teams leverage their existing skills while embracing the serverless paradigm.

MCP Server

MCP is an open protocol for AI agents to interact with external tools and data sources. It defines how AI assistants can discover, understand, and use various capabilities provided by external systems. This protocol allows AI models to extend their functionality beyond their own training data by accessing real-time information and executing specific tasks through standardized interfaces.

MCP servers implement this protocol by providing tools, resources, and contextual information that AI assistants can use via MCP clients. They serve as a knowledge bridge that gives AI assistants, such as Amazon Q Developer, Cline, and Cursor, the additional context needed to make informed decisions about cloud architecture and implementation. This is particularly valuable for serverless applications, where developers navigate multiple services, event patterns, and integration points to build scalable, performant applications.

AWS currently offers the AWS Lambda Tool MCP Server, which allows AI models to directly interact with existing Lambda functions as MCP tools without any code changes. This MCP server acts as a bridge between MCP clients and Lambda functions, allowing AI assistants to access and invoke Lambda functions.

Serverless MCP Server

The open-source AWS Serverless MCP launched today enhances the serverless development experience by providing AI coding assistants with comprehensive knowledge of serverless patterns, best practices, and AWS services. This MCP server acts as an intelligent companion, guiding developers through the entire application development lifecycle, from initial design to deployment, offering contextual assistance at each stage.

The new Serverless MCP server provides tools that cover many areas of serverless development. During the initial planning and setup phase, the MCP server helps developers initialize new projects using AWS Serverless Application Model (AWS SAM) templates, select appropriate Lambda runtimes, and set up project dependencies. This enables developers to quickly bootstrap new serverless applications with the right configuration and structure.

As development progresses, the MCP server assists with building and deploying serverless applications. It provides tools for local testing, building deployment artifacts, and managing deployments. For web applications, the MCP server offers specialized support for deploying backend, frontend, or full-stack applications, and setting up custom domains.

The MCP server also emphasizes operational excellence through comprehensive observability tools, helping developers to effectively monitor application performance and troubleshoot issues. Throughout the development process, the server provides contextual guidance for infrastructure as code (IaC) decisions, Lambda-specific best practices, and event schemas for Lambda event source mappings (ESMs).

Serverless MCP Server in action

To demonstrate the capabilities of the Serverless MCP Server, this example walks you through a scenario of creating, deploying, and troubleshooting a serverless application.

Prerequisites and installation

To get started, download the AWS Serverless MCP Server from GitHub or Python Package Index (PyPi) and follow the installation instructions. You can use this MCP server with any AI coding assistant of your choice, such as Q Developer, Cursor, Cline, etc. The walkthrough example in this post uses Cline.

Add the following code to your MCP client configuration. The Serverless MCP Server uses the default AWS profile by default. Specify a value in AWS_PROFILE if you want to use a different profile. Similarly, adjust the AWS Region and log level values as needed.

{
  "mcpServers": {
    "awslabs.aws-serverless-mcp": {
      "command": "uvx",
      "args": [
        "awslabs.aws_serverless_mcp_server@latest"
      ],
      "env": { 
        "AWS_PROFILE": "your-aws-profile",
        "AWS_REGION": "us-east-1",
        "FASTMCP_LOG_LEVEL": "ERROR"
      }
    }
  }
}

The Serverless MCP Server incorporates built-in guardrails to ensure secure and controlled development. By default, the MCP server operates in a read-only mode, allowing only non-mutating actions. This safety-first approach allows you to explore serverless capabilities and architectural patterns while preventing unintended changes to your applications or infrastructure. The server also restricts access to Amazon CloudWatch Logs by default, protecting sensitive operational data from exposure to AI assistants.

As your development needs evolve, you can selectively override these security defaults. The --allow-write flag enables mutating operations for tasks such as deployments and updates, while --allow-sensitive-data-access provides access to CloudWatch Logs for debugging and troubleshooting. Consider enabling these permissions only when necessary and in appropriate development contexts.

Creating and deploying a serverless application

Imagine that you want to build a to-do list web application. Start by prompting your AI assistant.

I want to build a new to-do list web application in a new workspace. I want to add, list, and delete to-dos. Would AWS Lambda be a good choice for this?

The agent uses the get_lambda_guidance_tool to receive tailored guidance based on the use case and the inferred event source, API Gateway in this case. Then, you want to better understand how to deploy the application to AWS.

I later want to deploy the application to AWS. Which Infrastructure as Code tool would be best for this?

There are several ways to deploy your functions to AWS such as AWS SAM or the AWS Cloud Development Kit (AWS CDK). The model opts to get more information before making a recommendation. It selects the get_iac_guidance_tool from the Serverless MCP Server.

The Serverless MCP Server can also assist you with interacting with the AWS Serverless Application Model Command Line Interface (AWS SAM CLI) as well as deploying application-based blueprints such as backend, frontend, or full-stack applications.

Before the deployment, test the function locally to verify that it works correctly.

I want to test my Lambda function locally before deploying it. Can you invoke the “TodoFunction” from my SAM project with a GET request?

Now that you are confident that the application works, you want to deploy the backend logic to AWS. So, you prompt the agent to deploy your app. It selects the deploy_webapp tool and provides the tool with arguments to deploy the app, including backend deploymentType. This tool uses the AWS Lambda Web Adapter framework, allowing you to easily deploy applications written in standard web frameworks like Express or Next.js, without any additional web adapters.

The agent can also check on the status of a deployment to make sure that it completes successfully.

Your application is now deployed to AWS and ready to serve traffic.

Troubleshooting the serverless application

The Serverless MCP Server also supports you in testing and troubleshooting your Lambda functions. It provides valuable context to AI assistants in identifying and remediating issues. For example, you can use your agent to check for any issues with your application.

Check the logs and metrics of the todo app for any issues

The model can analyze the logs and metrics and offer recommendations such as adjusting memory allocation.

The Serverless MCP Server tools provide the assistant with the additional context it needs to identify issues and generate recommendations.

In this example, the analysis and recommendations are:

Log Analysis

I’ve checked the logs for all three Lambda functions of your todo app, looking specifically for errors:

• ListTodosFunction: No errors detected
• AddTodoFunction: No errors detected
• DeleteTodoFunction: No errors detected

All functions are operating normally with successful executions and no error logs.

Performance Metrics

Lambda Function Performance
• Memory usage is reasonable at 100–106 MB out of 512 MB allocated (about 20% utilization)
• Fast execution durations for warm starts: 85–195 ms range
• No throttling or out-of-memory errors detected
• No function errors or exceptions in the logs

API Gateway Metrics
• Total Requests: 11 requests recorded
• Average Latency: 797 ms
• P95 Latency: 3364 ms (high)
• 4XX Errors: 0 (no client errors)
• 5XX Errors: 1 (one server error detected)

Issues Identified

The log analysis is clean with no errors, but the metrics reveal one potential issue:

  1. One 5XX Error in API Gateway: There was a single server-side error recorded in the API Gateway logs. Since there are no corresponding errors in the Lambda function logs, this might be related to:
    • A timeout (API Gateway taking too long to respond)
    • An integration issue between API Gateway and Lambda
    • A temporary network issue
  2. Relatively High P95 Latency: The 95th percentile latency of 3364 ms is quite high compared to the average. This suggests some outlier requests are taking significantly longer to complete.

Recommendations

  1. Monitor the 5XX error rate as it resurfaces.
  2. Consider implementing more detailed logging at the edge of the error path.
  3. Investigate the cause of the high P95 latency. Check for cold starts, payload size, or network latency as likely culprits.
  4. Consider enabling API Gateway and Lambda performance dashboards for more granular, historical latency and error metrics.
  5. Continue to monitor memory and duration metrics to ensure performance remains healthy as traffic increases.

Features supported by the Serverless MCP Server

The Serverless MCP Server provides several MCP tools, which can be classified into four categories.

  1. Serverless application lifecycle
    • sam_init_tool: Initializes a new AWS SAM project with the chosen runtime and dependencies.
    • sam_build_tool: Builds a serverless application using the AWS SAM CLI and prepares deployment artifacts.
    • sam_deploy_tool: Deploys a serverless application to AWS, managing artifact upload and stack creation.
    • sam_local_invoke_tool: Locally invokes a Lambda function for testing with custom events and environments.
  2. Web application deployment and management
    • deploy_webapp_tool: Deploys backend, frontend, or fullstack web applications to Lambda using the Lambda Web Adapter.
    • update_frontend_tool: Updates the frontend assets and optionally invalidates the Amazon CloudFront cache.
    • configure_domain_tool: Configures a custom domain, includes certificate and DNS setup.
  3. Observability
    • sam_logs_tool: Retrieves logs, and supports filtering and time range selection.
    • get_metrics_tool: Fetches specified metrics.
  4. Guidance, IaC templates, and deployment help
    • get_iac_guidance_tool: Provides guidance for selecting IaC tools.
    • get_lambda_guidance_tool: Offers advice on when to use Lambda for specific runtimes and use cases.
    • get_lambda_event_schemas_tool: Returns event schemas for Lambda integrations.
    • get_serverless_templates_tool: Supplies example AWS SAM templates for different serverless application types.
    • deployment_help_tool: Provides help and status information about deployments.
    • deploy_serverless_app_help_tool: Offers instructions for deploying serverless applications to Lambda.

Visit the Serverless MCP Server documentation for the full list of tools and resources.

Best practices and considerations

When building serverless applications with the AWS Serverless MCP Server, start by using its AI-assisted guidance for architectural decisions. Throughout development, use its guidance tools to make informed decisions about service selection, event patterns, and infrastructure design. Before deploying to AWS, use the Serverless MCP Server’s local testing capabilities to validate your application’s behavior. This approach helps ensure your application aligns with AWS best practices.

Robust monitoring and observability are critical to reliably operate your applications running in production. Use the Serverless MCP Server tools for deployment monitoring and setting up logging and metrics. This helps track application performance and quickly identify potential issues.

Conclusion

The open-source AWS Serverless MCP Server streamlines serverless application development by providing AI-assisted guidance throughout the development lifecycle. By combining AI assistance with serverless expertise, it enables developers to build and deploy applications more efficiently. The Serverless MCP Server’s toolset supports the complete development process, from initialization to observability, while helping developers implement AWS best practices.

As organizations continue to adopt serverless computing, tools that streamline development and accelerate delivery become increasingly valuable. AWS will continue to expand the collection of MCP servers for developers building serverless applications and refine existing tools based on customer feedback and emerging serverless development patterns.

To get started, visit the GitHub repository and explore the documentation. Share your experiences and suggestions through the GitHub repository to improve the MCP server’s capabilities and help shape the future of AI-assisted serverless development.

For more serverless learning resources, visit Serverless Land.

Enhancing multi-account activity monitoring with event-driven architectures

Post Syndicated from Anton Aleksandrov original https://aws.amazon.com/blogs/compute/enhancing-multi-account-activity-monitoring-with-event-driven-architectures/

Enterprise cloud environments are growing increasingly complex as they scale, with organizations managing hundreds to thousands of Amazon Web Services (AWS) accounts across multiple business units and AWS Regions. Organizations need efficient ways to collect, transport, and analyze activity data for threat detection and compliance monitoring. This presents unique challenges for enterprise Application Security (AppSec) teams, cloud security vendors, and DevSecOps professionals, because traditional polling-based monitoring approaches struggle to provide real-time activity insights needed for modern cloud operations.

In this post, you will learn to use AWS CloudTrail and Amazon EventBridge for real-time cloud activity monitoring and automated response.

Overview

As organizations expand their cloud footprint, account activity monitoring that comprehensively tracks user actions and successfully identifies security threats becomes crucial for threat detection and compliance. Although AWS provides native tools—such as CloudTrail for API activity capture, EventBridge for real-time event routing, AWS Organizations for multi-account management, and AWS Config for resource evaluation—many enterprises struggle with the volume of activities while maintaining efficiency and controlling costs. Organizations need to carefully architect solutions to effectively use these tools as their environments scale.

Traditional polling-based techniques, which worked well for smaller environments, can become unsustainable when scaled to enterprise deployments, where the volume of activity data grows exponentially with each new account and service. API polling limitations, growing data volumes, and increasing demand for real-time analysis are pushing teams to rethink their architectural approach.

Figure 1. Poll model, periodically retrieving the latest state.

Adopting push-based event-driven architectures offers a compelling solution for AppSec teams and cloud security vendors facing these challenges. Using AWS services, such as CloudTrail and EventBridge, allows these teams and vendors to build scalable activity monitoring solutions that overcome the limitations of traditional polling-based approaches and provide real-time notifications across thousands of AWS accounts. This approach not only enables security use cases but also supports broader real-time operational monitoring, compliance reporting, and automation requirements.

“By integrating AWS CloudTrail and Amazon EventBridge, we’ve built a scalable architecture to monitor activity across thousands of AWS accounts. This provides the visibility needed to detect threats in real time and protect large, distributed AWS environments.” — Rob Solomon, Senior Cloud Solution Architect, CrowdStrike

Solution components

Enterprise AppSec teams and cloud security vendors share common requirements when building multi-account monitoring solutions. They need to efficiently collect activity data across thousands of accounts, transport it to a centralized location for analysis, and process it in real-time to detect threats and compliance violations. The solution must scale seamlessly from dozens to thousands of accounts while remaining highly-performant and cost-efficient. At its core, a scalable multi-account activity monitoring solution consists of three components: activity data collection, cross-account transport to a centralized location, and processing. In the following sections, you will learn how AppSec teams and cloud security vendors can implement each step efficiently while avoiding common pitfalls.

Figure 2. Push model. Account activity is collected at the source, and pushed to the AppSec or cloud security vendor account for further processing.

Data collection strategies

Many teams begin their cloud activity monitoring journey by polling the resource status through service management APIs. Although this approach works good for retrieving the latest resource state on-demand, its fundamental limitation is inability to detect state changes efficiently, necessitating continuous querying of all resources at fixed intervals. Consider a scenario where you’re monitoring 1,000 accounts, with 100 resources in each account. A single polling cycle would necessitate 100,000 API requests, consuming over 28 million API calls daily if running at five-minute intervals. This inefficiency compounds as environments grow, leading to throttling issues, increased costs, and scaling challenges.

AWS Config improved upon this by offering continuous resource configuration tracking without manual polling. Although this works excellent for configuration compliance and a history of changes for auditing, AWS Config reports changes on a best-effort basis and is not optimal for real-time threat detection.

To overcome this constraint, your solution can use services such as CloudTrail and EventBridge as primary data sources, complemented by intelligent on-demand targeted API polling. CloudTrail records API activity across AWS services, providing a detailed history of actions taken by users, roles, and AWS services in your accounts. Over 250 AWS services automatically report their activity and API calls to CloudTrail and EventBridge in real-time. This allows you to capture this information, providing a detailed history of actions taken in your accounts, and enabling security analysis, resource state change tracking, and compliance audit.

Figure 3. Over 250 AWS services are automatically emitting activity events to CloudTrail.

When a resource state changes, commonly as a result of a management API call, the affected service sends an event to CloudTrail and EventBridge. Your monitoring solution can examine the event payload to determine if polling for supplementary data is necessary, particularly when the initial payload lacks complete information. This provides you with comprehensive service coverage with reduced maintenance effort. This hybrid approach guarantees delivery of activity data to eliminate monitoring blind spots, while significantly reducing AWS management API quota consumption.

Cross-account data transport

Your solution should transport activity data from thousands of tenant accounts into a small number of centralized accounts, such as a regional AppSec account, for further processing and analysis. The solution must be secure, scalable, resilient, and cost-efficient while maintaining real-time delivery.

The most direct way to achieve it is to enable Amazon S3 event notifications for new objects that are created in the CloudTrail trails S3 bucket. When you receive the notification, you can retrieve and process new activities.

Figure 4. Exporting CloudTrail events into an S3 bucket and retrieving after receiving a notification.

This direct way to consume CloudTrail events has one important consideration: typically it can take an average of five minutes to deliver events to Amazon S3. Teams and vendors looking for lower mean-time-to-detect (MTTD) and mean-time-to-respond (MTTR) should evaluate transporting CloudTrail events across accounts with EventBridge, which provides close-to-real-time delivery.

Transporting events with EventBridge

EventBridge is a serverless event router that connects applications. It receives events from various sources, such as CloudTrail, and routes them to multiple targets based on defined rules.

Using EventBridge for cross-account data transport comes with several major benefits:

There are two approaches you can take for delivering cross-account events with EventBridge: direct service-to-service or service-to-API-endpoint.

The first approach uses the EventBridge direct bus-to-bus and bus-to-service delivery capabilities. This method is most suitable when you want AWS to handle data ingestion on the receiving end. The delivery target is always either an EventBridge bus, or another AWS service, such as an Amazon Simple Queue Service (Amazon SQS) queue, Amazon Kinesis Data Streams stream, or an AWS Lambda function. With support for up to 18,750 target invocations per second and native AWS Identity and Access Management (IAM) integration, this method is particularly suitable for large multi-account deployments.

The second approach uses the EventBridge API destinations feature. This method is most suitable when you have existing HTTP-based ingestion endpoints in place. Although it offers lower throughput, it provides greater flexibility for ingestion endpoint and authentication methods implementation, making it attractive for AppSec teams and cloud security vendors integrating with existing ingestion infrastructure.

Figure 5. Emitting CloudTrail events in real-time through EventBridge.

The following table summarizes two approaches for transporting events across accounts with EventBridge.

Direct bus-to-bus or bus-to-service API destinations
Data ingestion implementation effort Minimal Needed
Default target invocations per second (TPS) quotas Up to 18,750 (region dependent) Up to 300 (region dependent)
Can the TPS quota be increased Yes Yes
Authorization support Native AWS IAM, fully handled by AWS Basic, OAuth2, API Key. You’re responsible for implementing credentials validation during ingestion.
Cross-account delivery costs $1 per million events $0.20 per million events

Go to the EventBridge quotas and pricing pages for more details.

Processing architecture

Processing would commonly be done by existing products and services the AppSec team or cloud security vendor provides for activity analysis. The architecture for event processing pipeline operating at enterprise scale must consider design decisions to handle large and potentially irregular event volumes while maintaining high performance, as shown in the following figure.

Figure 6. An activity event processing pipeline, with priority-based processing.

Use the following best practices for a robust processing architecture:

  • Buffer ingested events Use services such as Amazon SQS, Amazon Kinesis Data Streams, or Amazon Managed Streaming for Apache Kafka to buffer incoming events, handle traffic surges, and make sure of reliable processing.
  • Use serverless services that scale automatically, or invest in automated scaling mechanisms that adjust processing capacity based on event volume
  • Minimize polling: Resort to intelligent on-demand polling, only poll when you need additional data that is not available in the CloudTrail event payload.
  • Routing and classification: Rather than processing all events equally, implement intelligent classification and routing early in your pipeline. Security-related events such as IAM changes or security group modifications should take priority over routine activities or data events. This approach helps to control costs while maintaining rapid detection of important security events.
  • Cost optimization: At the enterprise scale, cost optimization becomes crucial. Use EventBridge rules in source accounts to filter out irrelevant events before they enter your processing pipeline. Consider implementing regional collection points to optimize data transfer costs. When using Lambda functions for data processing, use batch processing to reduce invocation costs. Evaluate which event types must be delivered in real-time through EventBridge, which event types can be delayed and collected through S3 bucket export, and which events should be discarded.
  • Observability: Monitor the ingestion and processing throughput to react to potential slowdowns early. Detect when source accounts are approaching EventBridge quotas. Consider using AWS Service Quotas to request quota increases automatically through APIs.
  • Cross-Region considerations: Design your architecture to support efficient cross-Region event collection while respecting data sovereignty requirements. Consider implementing regional processing nodes with centralized aggregation for global security analysis.
  • Integration patterns: Modern security solutions must integrate with existing security tools and workflows. Implement standardized output formats that allow seamless integration with SIEM systems, ticketing platforms, and automation frameworks. Consider publishing security findings back to EventBridge buses to enable automated remediation workflows. If you’re a cloud security vendor, then consider integrating with EventBridge as an SaaS partner.

Conclusion

Event-driven architectures present a powerful opportunity for building scalable multi-account activity monitoring solutions. Using services such as AWS CloudTrail and Amazon EventBridge allows teams to overcome the limitations of traditional polling-based approaches while achieving close to real-time delivery.The shift to event-driven security monitoring isn’t just an architectural choice—it’s becoming a necessity for teams operating at enterprise scale. This approach enables security teams to achieve the real-time threat detection capabilities needed in today’s cloud environments while maintaining operational efficiency and cost control.

Powering hybrid workloads with Amazon API Gateway

Post Syndicated from Mankaran Singh original https://aws.amazon.com/blogs/compute/powering-hybrid-workloads-with-amazon-api-gateway/

Amazon API Gateway can provide a single-entry point for all incoming API requests for Hybrid Workloads. You can use API Gateway to expose your resources in Amazon Virtual Private Cloud (VPC) and on-premises as REST APIs to external consumers. It provides a layer of abstraction between the API consumers and the backend services, allowing for centralized control. Routing all traffic through the API Gateway lets builders centrally enforce authentication, authorization, rate limiting, and other security features. This blog post describes how to configure API Gateway as an entry point to your on-premises resources.

Hybrid workloads can take advantage of API Gateway acting as single-entry point and provide a consistent interface for cloud and on-premises private API’s. You can connect API Gateway to resources within your private network through VPC link.

Figure 1 – private connectivity through VPC link

When private resources are located in different VPCs or AWS accounts, you can use AWS Transit Gateway or VPC peering to connect them.

Figure 2 – private connectivity through AWS Transit Gateway

You can also connect API Gateway to private resources hosted in your on-premises network.

Prerequisite

This blog assumes that you have an on-premises server hosting an API. Private connectivity between your AWS VPC and on-premises is needed, follow implementation step 1 for establishing private connectivity.

Solution overview

Figure 3 illustrates how to connect API Gateway’s REST API to on-premises application. The following steps detail the setup process.

Figure 3 – REST API architecture diagram for On-Premise applications

Implementation

The proposed solution can be implemented in six major steps:

Step 1. Enable VPC communication with on-premises network
Step 2. Setup Network Load Balancer for private integration with API gateway
Step 3. Create the VPC link
Step 4. Configure the API Gateway
Step 5. Create integration with VPC link
Step 6. Deploy the API

Step 1. Enable VPC communication with on-premises network

In this step we setup connectivity between Amazon VPC and on-premises network

  1. Create a VPC if one isn’t already configured.
  2. If no private connection between the VPC and your on-premises network exists, use either Virtual Private Gateway or AWS Transit Gateway to setup AWS Site-to-Site VPN or AWS Direct Connect.

Step 2. Setup Network Load Balancer for private integration with API gateway

In this step we setup Network Load Balancer required for private integration with API Gateway

  1. Sign in to the AWS Management Console and open the Amazon EC2 console at Amazon EC2 console
  2. Configure target group for your Network Load Balancer.
    Target group is used for request routing to your application. You will register on-premises server IPs in the target group. The load balancer checks the health of targets in this target group using the health check settings defined for the target group.

    1. Open the Amazon EC2 console at Amazon EC2 console.
    2. In the navigation pane, under Load Balancing, choose Target Groups.
    3. Choose Create target group.
    4. Keep the target type as IP addresses
    5. For Target group name, enter a name for the new target group.
    6. For Protocol, choose TCP, and for Port, choose the port where your application is running.
    7. For VPC, select the VPC created in PART A.
    8. For Health checks, keep the default settings.
    9. Choose Next.
    10. On the Register targets page, complete the following steps:
      1. Select the network as Other private IP address and Availability Zone as All
      2. Enter the IP addresses and port of the on-premises application, and then choose Include as pending below.
    11. Choose Create target group.

      Figure 4 – Amazon EC2 console create target group

  3. Configure your load balancer and listener
    To create a Network Load Balancer, you must first provide basic configuration information for your load balancer, such as a name, scheme, and IP address type. Then provide information about your network, and one or more listeners. A listener is a process that checks for connection requests. It is configured with a protocol and a port for connections from clients to the load balancer.

    1. For Load balancer name, enter a name for your load balancer.
    2. For Scheme and IP address type, keep the default values.
    3. For Network mapping, select the VPC that was previously created. Select one subnet each in at least two availability zones for high availability. By default, AWS assigns an IPv4 address to each load balancer node from the subnet for its Availability Zone.
    4. For Security groups, you will have a default security group associated for your VPC. Remove the default security group as it is not required for this setup.Review your configuration, and choose Create load balancer.
    5. For Listeners and routing, select the protocol as TCP and port of your application, and select the target group from the list. This configures a listener that accepts TCP traffic on port that you specify and forwards traffic to the selected target group by default.
    6. Review your configuration, and choose Create load balancer.

      Figure 5 – Amazon EC2 console create load balancer

  4. Turn off security group evaluation for PrivateLink for your Network Load Balancer.
    1. Go to your Network Load Balancer.
    2. Select the Security tab.
    3. Choose Edit.
    4. Clear “Enforce inbound rules on PrivateLink traffic”.
    5. Save changes

      Figure 6 – Amazon EC2 console -> Load Balancers -> Security; turn off security group evaluation

Step 3. Create the VPC Link

In this step we create a VPC link to connect your API and your Network Load Balancer. After you create a VPC link, you create private integrations to route traffic from your API to resources in your VPC through your VPC link and Network Load Balancer. To create VPC link, you need to do the following:

  1. Open the API Gateway console at Amazon API Gateway console
  2. Click on VPC Links in the navigation pane.
  3. Click on Create VPC Link and provide a name for the VPC link.
  4. Select the VPC link for REST APIs and provide the VPC link details following:
    1. For Name, enter the name for your VPC link
    2. For Description(optional), provide a description for your VPC link.
    3. For Target NLB, select the NLB created in the previous step from the dropdown.
  5. Choose Create

    Figure 7 – Amazon API Gateway console create a VPC link

Step 4. Create the API Gateway

In this step we create API Gateway that will have private integration with the Network Load Balancer

  1. Go back to the API Gateway Console Amazon API Gateway console
  2. Choose Create API. Under REST API, choose Build.
  3. Create Regional REST API.
    1. For API details, select New API
    2. For API name, provide a name for your API
    3. For Description(optional), provide a description for your API.
    4. For API endpoint type, select regional from the drop-down option.
  4. Choose Create API.

    Figure 8 – Amazon API Gateway console create REST API

Step 5. Create integration with VPC link

In this step we integrate the VPC link with the API created in the previous step.

  1. Create Resource
    1. From API Gateway console select Create resource
    2. Under Resource details, specify the resource path and resource name
    3. Choose Create resource

      Figure 9 – Amazon API Gateway console create resource for VPC link integration

  2. Create Method
    1. From API Gateway console select Create method.
    2. For Method type, select the desired method.
    3. For Integration type, select VPC link.
    4. Turn on VPC proxy integration.
    5. For HTTP method, select desired method.
    6. For VPC link, select the VPC link from the dropdown menu that was created in the previous steps.
    7. For Endpoint URL, enter a URL for the NLB created in the previous steps along with the port number. For eg: http://nlb-api-integration-xxxxxxxxxxxxxxxx.elb.us-east-1.amazonaws.com:80/on-prem. Assuming the endpoint is going to retrieve /on-prem resource.
    8. Choose Create method.
With the proxy integration, the API is ready for deployment. Otherwise, you need to proceed to set up appropriate method responses and integration responses.

      Figure 10 – Amazon API Gateway console create method and provide method details

      Figure 11 – Amazon API Gateway console create method and provide method details

Step 6. Deploy the API

Final step is to deploy the API. You can do that by using the following steps:

  1. Choose Deploy API
  2. For Stage, select New stage.
  3. For Stage name, enter a stage name.
  4. For Description(optional), enter a description.
  5. Choose Deploy

    Figure 12 – Amazon API Gateway console deploy the created API

Security

Security is the top priority at AWS and operates on a shared responsibility model between AWS and its customers. When managing hybrid APIs, implementing robust security measures is essential since these APIs serve as critical gateways to sensitive data and services. For detailed guidance on securing your REST APIs using API Gateway, please consult our documentation

Cleanup

To prevent incurring additional charges, remove the resources that were created during this walkthrough

  1. Open the API Gateway console.
  2. Select the APIs you created and select delete.
  3. Go to the VPC links in the navigation pane and select the VPC link created. Delete the VPC link.
  4. Within the EC2 console, go to load balancers in the navigation pane and delete the target group and NLB.

Conclusion

This post demonstrates how to configure API Gateway as an entry point for your on-premises resources, providing a unified API interface for your clients.

You can read more about working with API Gateway in AWS documentation and use these capabilities to create architectures to suit your specific requirements. For more serverless learning resources, visit Serverless Land.

Securing Amazon S3 presigned URLs for serverless applications

Post Syndicated from Raaga N.G original https://aws.amazon.com/blogs/compute/securing-amazon-s3-presigned-urls-for-serverless-applications/

Modern serverless applications must be capable of seamlessly handling large file uploads. This blog demonstrates how to leverage Amazon Simple Storage Service (Amazon S3) presigned URLs to allow your users to securely upload files to S3 without requiring explicit permissions in the AWS Account. This blog post specifically focuses on the security ramifications of using S3 presigned URLs, and explains mitigation steps that serverless developers can take to improve the security of their systems using S3 presigned URLs. Additionally, the blog post also walks through an AWS Lambda function that adheres to the provided recommendations, ensuring a robust and secure approach to handling S3 presigned URLs. For more information on S3 presigned URLs, see Working with presigned URLs.

Presigned URL Workflow for Serverless Applications

The following architecture diagram illustrates a serverless application that generates an S3 presigned URL. By using S3 presigned URLs, serverless applications can offload to S3 the computation required to receive files. The diagram captures a seven-step process between the client, Amazon API Gateway, the Lambda function, and S3.

A typical workflow to upload a file to a serverless application hosted on S3 includes the following steps:

  1. Client submits a request to upload a file.
  2. API Gateway receives the client request and invokes a Lambda function that then generates the S3 presigned URL.
  3. The Lambda function makes a getSignedUrl API call to S3.
  4. S3 returns the presigned URL for the object to be uploaded.
  5. The Lambda function returns a presigned URL to the API.
  6. Client receives the S3 presigned URL to upload the file.
  7. Client uploads the file directly to S3 using the presigned URL.

How to Secure Presigned URLs

When designing a serverless application that utilizes S3 presigned URLs to store data in S3, a developer must consider several primary security aspects. S3 presigned URLs are public resources that do not authenticate users, and anyone in possession of a valid S3 presigned URL can access the associated resource. Consequently, it is important to implement additional security measures to ensure that these URLs are not misused or accessed by unauthorized parties. The following blog post contains techniques you can use to make your presigned URLs more secure.

1. Add a Content-MD5 checksum using the X-Amz-Signed header

When you upload an object to S3, you can include a precalculated checksum of the object as part of your request. S3 will perform an integrity check and verify if the object sent is the same as the object received. S3 supports the use of MD5 checksums to verify the integrity of objects uploaded. You provide the MD5 digest by including a Content-MD5 header in the initial PUT request. Upon receiving the object, S3 will calculate the MD5 digest and compare it with the one you originally provided. The upload operation succeeds only if both MD5 digests match, ensuring end-to-end data integrity. If an unintended party gets their hands on the S3 presigned URL, then they will not be able to use it without possessing the same object. This provides protection against arbitrary file uploads.

The key element for a developer to remember is that when the client uploads the file to the S3 presigned URL, it must supply the correct MD5 in Base64 using the Content-MD5 header. Developers can see a sample serverless application with client-side code to extract the MD5 digest, request a S3 presigned URL, and upload a file in this GitHub repository. This sample application uses NodeJS v20 in the Lambda function.

2. Expire the S3 presigned URLs 

An S3 presigned URL remains valid for the period of time specified when the URL is generated. It is important to ensure that the S3 presigned URL does not remain accessible for longer than required as it can be reused when still valid. You can define the expiration time of the S3 presigned URL by either passing X-Amz-Expires as a query parameter or by setting the expiresIn parameter when using the AWS SDK for JavaScript.

S3 validates the expiration time and date at the time of initial HTTP Request. However, to support situations where the connection drops and the client needs to restart uploading a file, you may want your S3 presigned URL to remain valid for the entire anticipated time needed to upload the file to S3. The challenge is to generate an S3 presigned URL that is valid long enough to accommodate the file’s upload, yet still short enough that you prevent reuse.

A solution we propose to overcome these challenges is to dynamically set the S3 presigned URL’s expiration time by using the browser Network Information API. Using this new API, when the client browser places the initial request for an S3 presigned URL, the client also transmits the file’s size and the network type, so the Lambda function can calculate the anticipated transfer time.

Within the Lambda function, we can now estimate the transfer time for this size of file on this type of network, using sample code as featured in this GitHub repository.

With the estimated transfer time calculated, the Lambda function can now request the S3 presigned URL and set the expiresIn parameter to the transfer time, resulting in an S3 presigned URL that is only available for the time needed to upload that size of file on this type of network.

If you are using the AWS SDK, you may also be using AWS Signature Version 4 (SigV4) to sign your requests. To create a defense in depth approach, which will place a ceiling on total expiration time, you can utilize condition keys in bucket policies. For an example policy, see Limiting presigned URL capabilities.

3. Generating a UUID to replace the uploaded filename

When an application allows a user to upload files, the application exposes itself to various security threats, such as path traversal attacks. Path traversal vulnerabilities allow attackers to access files that are not meant to be accessed or to overwrite files outside the intended directory structure. In order to secure your applications against such vulnerabilities, the most effective approach is to incorporate user input validation and sanitization. You can sanitize the filename by replacing it with a generated UUID (Universally Unique Identifier).

You can see an example function in the server-side code for Lambda in this GitHub repository.

4. Applying the Principle of Least Privilege and using a separate Lambda function to create S3 presigned URLs

The capabilities of an S3 presigned URL are constrained by the permissions of the principal that created it. To offer fine-grained access, the very first step in limiting use of an S3 presigned URL should be building a specific Lambda function that generates these URLs. By having a Lambda function dedicated to this purpose, you do not risk an overly permissive Lambda function. The second step is to limit your specific Lambda function’s access to S3.

Adhering to the Principle of Least Privilege, it’s important to restrict the Lambda function’s permissions to only the required prefixes in the bucket and allow it to perform only the required actions on the bucket, instead of granting full bucket access. This minimizes the potential attack surface and mitigates the risk of unintended data exposure or modification. It is important to limit the permissions to the minimum required set of actions and resources.

This example AWS Identity and Access Management (IAM) policy demonstrates how to grant the Lambda function read access (GET) to objects within the "Example-Prefix" prefix of a specific S3 bucket. The IAM policy is attached to the Lambda function via an execution role, which together establish what actions the Lambda function can perform.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "ReadStatement",
      "Action": [
        "s3:GetObject"
      ],
      "Resource": [
        "arn:aws:s3:::EXAMPLE-BUCKET/Example-Prefix/",
        "arn:aws:s3:::EXAMPLE-BUCKET/Example-Prefix/*"
      ],
      "Effect": "Allow"
    }
  ]
}

This example IAM policy demonstrates how to grant the Lambda function permissions to upload (PUT) objects within the "Example-Prefix" prefix of a specific S3 bucket.

{   
    "Version": "2012-10-17",
    "Statement": [
        {   
            "Sid": "UploadStatement",
            "Action": [
                "s3:PutObject",
                "s3:ListBucket"
            ],
            "Resource": [
                "arn:aws:s3:::EXAMPLE-BUCKET/Example-Prefix/",
                "arn:aws:s3:::EXAMPLE-BUCKET/Example-Prefix/*"
            ],
            "Effect": "Allow"
        }
    ]
}

This approach will ensure that your Lambda function possesses the minimum required permissions to perform its intended tasks and reduces the risk of unintended data access or modification.

If you want to restrict the use of S3 presigned URLs and all S3 access to a particular network path, you can also define a network-path restriction policy on the S3 Bucket. This restriction on the bucket requires that all requests to the bucket originate from a specified network. AWS Prescriptive Guidance says, an extension of least privilege is to maintain a data perimeter that’s consistent with your organization’s needs. The goal of an AWS perimeter is to ensure that the access is allowed only if the request is coming from a trusted entity, for trusted resources from a trusted network. These data perimeters are applicable to S3 presigned URLs as well.

5.Creating one-time use S3 presigned URLs

Serverless applications developers may want each S3 presigned URL to only be used once. Developers can incorporate a token-based mechanism to facilitate secure one-time use of an S3 presigned URL. This involves generating unique tokens for each authorized user or client and associating these tokens with the S3 presigned URLs. When a client attempts to access the resource using the S3 presigned URL, they must provide the corresponding token for validation. This additional layer of security ensures that only authorized entities can access the S3 presigned URLs and the associated resources. Furthermore, you can leverage a database to track the issued tokens and expire them after each use. A solution to implement such a mechanism has been discussed in detail in How to securely transfer files with presigned URLs.

Cleaning up

You may clean up the sample application by deleting the API Gateway, Lambda function, and S3 bucket. In addition, please do not forget to delete any IAM execution roles you created for the Lambda function.

Conclusion

In this blog we have discussed various considerations that a developer must make when designing an application that leverages S3 presigned URLs. By incorporating robust security measures, such as proper access control, input sanitization, expiration handling and integrity checks, developers can mitigate potential risks when using S3 presigned URLs.

Petabyte-scale data migration made simple: AppsFlyer’s best practice journey with Amazon EMR Serverless

Post Syndicated from Roy Ninio original https://aws.amazon.com/blogs/big-data/petabyte-scale-data-migration-made-simple-appsflyers-best-practice-journey-with-amazon-emr-serverless/

This post is co-written with Roy Ninio from Appsflyer.

Organizations worldwide aim to harness the power of data to drive smarter, more informed decision-making by embedding data at the core of their processes. Using data-driven insights enables you to respond more effectively to unexpected challenges, foster innovation, and deliver enhanced experiences to your customers. In fact, data has transformed how organizations drive decision-making, but historically, managing the infrastructure to support it posed significant challenges and required specific skill sets and dedicated personnel. The complexity of setting up, scaling, and maintaining large-scale data systems impacted agility and pace of innovation. This reliance on experts and intricate setups often diverted resources from innovation, slowed time-to-market, and hindered the ability to respond to changes in industry demands.

AppsFlyer is a leading analytics and attribution company designed to help businesses measure and optimize their marketing efforts across mobile, web, and connected devices. With a focus on privacy-first innovation, AppsFlyer empowers organizations to make data-driven decisions while respecting user privacy and compliance regulations. AppsFlyer provides tools for tracking user acquisition, engagement, and retention, delivering actionable insights to enhance ROI and streamline marketing strategies.

In this post, we share how AppsFlyer successfully migrated their massive data infrastructure from self-managed Hadoop clusters to Amazon EMR Serverless, detailing their best practices, challenges to overcome, and lessons learned that can help guide other organizations in similar transformations.

Why AppsFlyer embraced a serverless approach for big data

AppsFlyer manages one of the largest-scale data infrastructures in the industry, processing 100 PB of data daily, handling millions of events per second, and running thousands of jobs across nearly 100 self-managed Hadoop clusters. The AppsFlyer architecture is comprised of many data engineering open source technologies, including but not limited to Apache Spark, Apache Kafka, Apache Iceberg, and Apache Airflow. Although this setup has powered operations for years, the growing complexity of scaling resources to meet fluctuating demands, coupled with the operational overhead of maintaining clusters, prompted AppsFlyer to rethink their big data processing strategy.

EMR Serverless is a modern, scalable solution that alleviates the need for manual cluster management while dynamically adjusting resources to match real-time workload requirements. With EMR Serverless, scaling up or down happens within seconds, minimizing idle time and interruptions like spot terminations.

This shift has freed engineering teams to focus on innovation, improved resilience and high availability, and future-proofed the architecture to support their ever-increasing demands. By only paying for compute and memory resources used during runtime, AppsFlyer also optimized costs and minimized charges for idle resources, marking a significant step forward in efficiency and scalability.

Solution overview

AppsFlyer’s previous architecture was built around self-managed Hadoop clusters running on Amazon Elastic Compute Cloud (Amazon EC2) and handled the scale and complexity of the data workflows. Although this setup supported operational needs, it required substantial manual effort to maintain, scale, and optimize.

AppsFlyer orchestrated over 100,000 daily workflows with Airflow, managing both streaming and batch operations. Streaming pipelines used Spark Streaming to ingest real-time data from Kafka, writing raw datasets to an Amazon Simple Storage Service (Amazon S3) data lake while simultaneously loading them into BigQuery and Google Cloud Storage to build logical data layers. Batch jobs then processed this raw data, transforming it into actionable datasets for internal teams, dashboards, and analytics workflows. Additionally, some processed outputs were ingested into external data sources, enabling seamless delivery of AppsFlyer insights to customers across the web.

For analytics and fast queries, real-time data streams were ingested into ClickHouse and Druid to power dashboards. Additionally, Iceberg tables were created from Delta Lake raw data and made accessible through Amazon Athena for further data exploration and analytics.

With the migration to EMR Serverless, AppsFlyer replaced its self-managed Hadoop clusters, bringing significant improvements to scalability, cost-efficiency, and operational simplicity.

Spark-based workflows, including streaming and batch jobs, were migrated to run on EMR Serverless and take advantage of the elasticity of EMR Serverless, dynamically scaling to meet workload demands.

This transition has significantly reduced operational overhead, alleviating the need for manual cluster management, so teams can focus more on data processing and less on infrastructure.

The following diagram illustrates the solution architecture.

This post reviews the main challenges and lessons learned by the team at AppsFlyer from this migration.

Challenges and lessons learned

Migrating a large-scale organization like AppsFlyer, with dozens of teams, from Hadoop to EMR Serverless was a significant challenge—especially because many R&D teams had limited or no prior experience managing infrastructure. To provide a smooth transition, AppsFlyer’s Data Infrastructure (DataInfra) team developed a comprehensive migration strategy that empowered the R&D teams to seamlessly migrate their pipelines.

In this section, we discuss how AppsFlyer approached the challenge and achieved success for the entire organization.

Centralized preparation by the DataInfra team

To provide a seamless transition to EMR Serverless, the DataInfra team took the lead in centralizing preparation efforts:

  • Clear ownership – Taking full responsibility for the migration, the team planned, guided, and supported R&D teams throughout the process.
  • Structured migration guide – A detailed, step-by-step guide was created to streamline the transition from Hadoop, breaking down the complexities and making it accessible to teams with limited infrastructure experience.

Building a strong support network

To make sure the R&D teams had the resources they needed, AppsFlyer established a robust support environment:

  • Data community – The primary resource for answering technical questions. It encouraged knowledge sharing across teams and was spearheaded by the DataInfra team.
  • Slack support channel – A dedicated channel where the DataInfra team actively responded to questions and guided teams through the migration process. This real-time support significantly reduced bottlenecks and helped teams resolve issues quickly.

Infrastructure templates with best practices

Recognizing the complexity of the team’s migration, the DataInfra team had standardized templates to help teams start quickly and efficiently:

  • Infrastructure as code (IaC) templates – They developed Terraform templates with best practices for building applications on EMR Serverless. These templates included code examples and real production workflows already migrated to EMR Serverless. Teams could quickly bootstrap their projects by using these ready-made templates.
  • Cross-account access solutions – Operating across multiple AWS accounts required managing secure access between EMR Serverless accounts (where jobs run) and data storage accounts (where datasets reside). To streamline this, a step-by-step module was developed for setting up cross-account access using Assume Role permissions. Additionally, a dedicated repository was created, so teams can define and automate role and policy creation, providing seamless and scalable access management.

Airflow integration

As AppsFlyer’s primary workflow scheduler, Airflow plays a critical role, making it essential to provide a seamless transition for its users.

AppsFlyer developed a dedicated Airflow operator for executing Spark jobs on EMR Serverless, carefully designed to replicate the functionality of the existing Hadoop-based Spark operator. In addition, a Python package was made available across all Airflow clusters with the relevant operators. This approach minimized code changes, allowing teams to transition seamlessly with minimal modifications.

Solving common permission challenges

To streamline permissions management, AppsFlyer developed targeted solutions for frequent use cases:

  • Comprehensive documentation – Provided detailed instructions for handling permissions for services like Athena, BigQuery, Vault, GIT, Kafka, and many more.
  • Standardized Spark defaults configuration for teams to apply to their applications – Included built-in solutions for collecting lineage from Spark jobs running on EMR Serverless, providing accountability and traceability.

Continuous engagement with R&D teams

To promote progress and maintain alignment across teams, AppsFlyer introduced the following measures:

  • Weekly meetings – Weekly status meetings to review the status of each team’s migration efforts. Teams shared updates, challenges, and commitments, fostering transparency and collaboration.
  • Assistance – Proactive assistance was provided for issues raised during meetings to minimize delays. This made sure that the teams were on track and had the support they needed to meet their commitments.

By implementing these strategies, AppsFlyer transformed the migration process from a daunting challenge into a structured and well-supported journey. Key outcomes included:

  • Empowered teams – R&D teams with minimal infrastructure experience were able to confidently migrate their pipelines.
  • Standardized practices – Infrastructure templates and predefined solutions provided consistency and best practices across the organization.
  • Reduced downtime – The custom Airflow operator and detailed documentation minimized disruptions to existing workflows.
  • Cross-account compatibility – With seamless cross-account access, teams could run jobs and access data efficiently.
  • Improved collaboration – The data community and Slack support channel fostered a sense of collaboration and shared responsibility across teams.

Migrating an entire organization’s data workflows to EMR Serverless is a complex task, but by investing in preparation, templates, and support, AppsFlyer successfully streamlined the process for all R&D teams in the company.

This approach can serve as a model for organizations undertaking similar migrations.

Spark application code management and deployment

For AppsFlyer data engineers, developing and deploying Spark applications is a core daily responsibility. The Data Platform team focuses on identifying and implementing the right set of tools and safeguards that would not only simplify the migration to EMR Serverless, but also streamline ongoing operations.

There are two different approaches available for running Spark code on EMR Serverless: custom container images and JARs or Python files. At the beginning of the exploration, custom images looked promising because it allows greater customization than JARs, which should allow the DataInfra team smoother migration for existing workloads. After deeper research, it was realized that custom images have great power, but come with a cost that in large scale would need to be evaluated. Custom images presented the following challenges:

  • Custom images are supported as of version 6.9.0, but some of AppsFlyer’s workloads used earlier versions.
  • EMR Serverless resources run from the moment EMR Serverless begins downloading the image until workers are stopped. This means a payment is done for aggregate vCPU, memory, and storage resources during the image download phase.
  • They required a different continuous integration and delivery (CI/CD) approach than compiling a JAR or Python file, leading to operational work that should be minimized as much as possible.

AppsFlyer decided to go all in with JARs and allow only in unique cases, where the customization required the use of custom images. Eventually, it was realized that using non-custom images was suitable for AppsFlyer use cases.

CI/CD perspective

From a CI/CD perspective, AppsFlyer’s DataInfra team decided to align with AppsFlyer’s GitOps vision, making sure that both infrastructure and application code are version-controlled, built, and deployed using Git operations.

The following diagram illustrates the GitOps approach AppsFlyer adopted.

JARs continuous integration

For CI, the process in charge of building the application artifacts, several options have been explored. The following key considerations drove the exploration process:

  • Use Amazon S3 as the native JAR source for EMR Serverless
  • Support different versions for the same job
  • Support staging and production environments
  • Allow hotfixes, patches, and rollbacks

Using AppsFlyer’s current external package repository led to challenges, because it required them to build a custom delivery into Amazon S3 or a complex runtime ability to fetch the code externally.

Using Amazon S3 directly also had several alternative approaches:

  • Buckets – Use single vs. separated buckets for staging and production
  • Versions – Use Amazon S3 native object versioning vs. uploading a new file
  • Hotfix – Override the same job’s JAR file vs. uploading a new one

Finally, the decision was to go with immutable builds for consistent deployment across the environments.

Each Spark job git repository pushes to the main branch, triggers a CI process to validate the semantic versioning (semver) assignment, compiles the JAR artifact, and uploads it to Amazon S3. Each artifact is uploaded to three different paths according to the version of the JAR, and also include a version tag for the S3 object:

  • <BucketName>/<SparkJobName>/<major>"."<minor>"."<patch>/app.jar
  • <BucketName>/<SparkJobName>/<major>"."<minor>"/app.jar
  • <BucketName>/<SparkJobName>/<major>/app.jar

AppsFlyer can now have deep granularity and assign each EMR Serverless job to a pinpointed version. Some jobs can run with the latest major version, and other stability and SLA sensitive jobs require a lock to a specific patch version.

EMR Serverless continuous deployment

Uploading the files to Amazon S3 was the final step in the CI process, which then leads to a different CD process.

CD is done by changing the infrastructure code, which is Terraform based, to point to the new JAR that was uploaded to Amazon S3. Then the staging or production application can start using the newly uploaded code and the process can be considered deployed.

Spark application rollbacks

If they need an application rollback, AppsFlyer points the EMR Serverless job IaC configuration from the current impaired JAR version to the previous stable JAR version in the relevant Amazon S3 path.

AppsFlyer believes that every automation impacting production, like CD, requires a breaking glass mechanism for an emergency situation. In such cases, AppsFlyer can manually override the needed S3 object (JAR file) while still using Amazon S3 versions in order to have better visibility and manual version control.

Single-job vs. multi-job applications

When using EMR Serverless, one important architectural decision is whether to create a separate application for each Spark job or use an automatic scaling application shared across multiple Spark jobs. The following table summarizes these considerations.

Aspect Single-Job Application Multi-Job Application
Logical Nature Dedicated application for each job. Shared application for multiple jobs.
Shared Configurations Limited shared configurations; each application is independently configured. Allows shared configurations through spark-defaults, including executors, memory settings, and JARs.
Isolation Maximum isolation; each job runs independently. Maintains job-level isolation through distinct IAM roles despite sharing the application.
Flexibility Flexible for unique configurations or resource requirements. Reduces overhead by reusing configurations and using automatic scaling.
Overhead Higher setup and management overhead due to multiple applications. Lower administrative overhead but requires careful resource contention management.
Use Cases Suitable for jobs with unique requirements or strict isolation needs. Ideal for related workloads that benefit from shared settings and dynamic scaling.

By balancing these considerations, AppsFlyer tailored its EMR Serverless usage to efficiently meet the demands of diverse Spark workloads across their teams.

Airflow operator: Simplifying the transition to EMR Serverless

Before the migration to EMR Serverless, AppsFlyer’s teams relied on a custom Airflow Spark operator created by the DataInfra team.

This operator, packaged as a Python library, was integrated into the Airflow environment and became a key component of the data workflows.

It provided essential capabilities, including:

  • Retries and alerts – Built-in retry logic and PagerDuty alert integration
  • AWS role-based access – Automatic fetching of AWS permissions based on role names
  • Custom defaults – Setting Spark configurations and package defaults tailored for each job
  • State management – Job state tracking

This operator streamlined running Spark jobs on Hadoop and was highly tailored to AppsFlyer’s requirements.

When moving to EMR Serverless, the team chose to build a custom Airflow operator to align with their existing Spark-based workflows. They already had dozens of Directed Acyclic Graphs (DAGs) in production, so with this approach, they could maintain their familiar interface, including custom handling for retries, alerting, and configurations—all without requiring broad changes across the board.

This abstraction provided a smoother migration by preserving the same development patterns and minimizing the migration efforts of adapting to the native operator semantics.

The DataInfra team developed a dedicated, custom, EMR Serverless operator to support the following goals:

  • Seamless migration – The operator was designed to closely mimic the interface of the existing Spark operator on Hadoop. This made sure that teams could migrate with minimal code changes.
  • Feature parity – They added the features missing from the native operator:
    • Built-in retry logic.
    • PagerDuty integration for alerts.
    • Automatic role-based permission fetching.
    • Default Spark configurations and package support for each job.
  • Simplified integration – It’s packaged as a Python library available in Airflow clusters. Teams could use the operator just like they did with the previous Spark operator.

The custom operator abstracts some of the underlying configurations required to submit jobs to EMR Serverless, aligning with AppsFlyer’s internal best practices and adding essential features.

The following is from an example DAG using the operator:

return SparkBatchJobEmrServerlessOperator(
    task_id=task_id,  # Unique task identifier in the DAG

    jar_file=jar_file,  # Path to the Spark job JAR file on S3
    main_class="<main class path>",

    spark_conf=spark_conf,

    app_id=default_args["<emr_serverless_application_id>"],  # EMR Serverless app ID
    execution_role=default_args["<job_execution_role_arn>"],  # IAM role for job execution

    polling_interval_sec=120,  # How often to poll for job status
    execution_timeout=timedelta(hours=1),  # Max allowed runtime

    retries=5,  # Retry attempts for failed jobs
    app_args=[],  # Arguments to pass to the Spark job

    depends_on_past=True,  # Ensure sequential task execution

    tags={'owner': '<team_tag>'},  # Metadata for ownership
    aws_assume_role="<my_aws_role>",  # Role for cross-account access

    alerting_policy=ALERT_POLICY_CRITICAL.with_slack_channel(sc),  # Alerting integration
    owner="<team_owner>",

    dag=dag  # DAG this task belongs to
)

Cross-account permissions on AWS: Simplifying EMRs workflows

AppsFlyer operates across multiple AWS accounts, creating a need for secure and efficient cross-account access. EMR Serverless jobs are executed in the production account, and the data they process resides in a separate data account. To enable seamless operation, Assume Role permissions are used to verify that EMR Serverless jobs running in the production account can access the data and services in the data account. The following diagram illustrates this architecture.

Below is a diagram demonstrating the cross-account permissions AppsFlyer adopted:

Role management strategy

To manage cross-account access efficiently, three distinct roles were created and maintained:

  • EMR role – Used for executing and managing EMR Serverless applications in the production account. Integrated directly into Airflow workers to make it available for the DAGs on the dedicated team Airflow cluster.
  • Execution role – Assigned to the Spark job running on EMR Serverless. Passed by the EMR role in the DAG code to provide seamless integration.
  • Data role – Resides in the data account and is assumed by the execution role to access data stored in Amazon S3 and other AWS services.

To enforce access boundaries, each role and policy is tagged with team-specific identifiers.
This makes sure that teams can only access their own data and roles, minimizing unauthorized access to other teams’ resources.

Simplifying Airflow migration

A streamlined process to make cross-account permissions transparent for teams migrating their workloads to EMR Serverless was developed:

  1. The EMR role is embedded into Airflow workers, making it available for DAGs in the dedicated Airflow cluster for each team:
{
   "Version":"2012-10-17",
   "Statement":[
      "..."{
         "Effect":"Allow",
         "Action":"iam:PassRole",
         "Resource":"arn:aws:iam::account-id:role/execution-role",
         "Condition":{
            "StringEquals":{
               "iam:ResourceTag/Team":"team-tag"
            }
         }
      }
   ]
}
  1. The EMR role automatically passes the execution role to the job within the DAG code:
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": "sts:AssumeRole",
      "Resource": "arn:aws:iam::data-account-id:role/data-role",
      "Condition": {
        "StringEquals": {
          "iam:ResourceTag/Team": "team-tag"
        }
      }
    }
  ]
}
  1. The execution role assumes the data role dynamically during job execution to access the required data and services in the data account:

Allows the Execution Role in the Production account to assume the Data Role.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Principal": {
        "AWS": "arn:aws:iam::production-account-id:role/execution-role"
      },
      "Action": "sts:AssumeRole"
    }
  ]
}
  1. Policies, trust relationships, and role definitions are managed in a dedicated GitLab repository. GitLab CI/CD pipelines automate the creation and integration of roles and policies, providing consistency and reducing manual overhead.

Benefits of AppsFlyer’s approach

This approach offered the following benefits:

  • Seamless access – Teams no longer need to handle cross-account permissions manually because these are automated through preconfigured roles and policies, providing seamless and secure access to resources across accounts.
  • Scalable and secure – Role-based and tag-based permissions provide security and scalability across multiple teams and accounts. By using roles and tags, it alleviates the need to create separate hardcoded policies for each team or account. Instead, they can define generalized policies that scale automatically as new resources, accounts, or teams are added.
  • Automated management – GitLab CI/CD streamlines the deployment and integration of policies and roles, reducing manual effort while enhancing consistency. It also minimizes human errors, improves change transparency, and simplifies version management.
  • Flexibility for teams – Teams have the flexibility to use their own or native EMR Serverless operators while maintaining secure access to data.

By implementing a robust, automated cross-account permissions system, AppsFlyer has enabled secure and efficient access to data and services across multiple AWS accounts. This makes sure that teams can focus on their workloads without worrying about infrastructure complexities, accelerating their migration to EMR Serverless.

Integrating lineage into EMR Serverless

AppsFlyer developed a robust solution for column-level lineage collection to provide comprehensive visibility into data transformations across pipelines. Lineage data is stored in Amazon S3 and subsequently ingested into DataHub, AppsFlyer’s lineage and metadata management environment.

Currently, AppsFlyer collects column-level lineage from a variety of sources, including Amazon Athena, BigQuery, Spark, and more.

This section focuses on how AppsFlyer collects Spark column-level lineage specifically within the EMR Serverless infrastructure.

Collecting Spark lineage with Spline

To capture lineage from Spark jobs, AppsFlyer uses Spline, an open source tool designed for automated tracking of data lineage and pipeline structures.

AppsFlyer modified Spline’s default behavior to output a customized Spline object that aligns with AppsFlyer’s specific requirements. AppsFlyer adapted the Spline integration into both legacy and modern environments. In the pre-migration phase, they injected the Spline agent into Spark jobs through their customized Airflow Spark operator. In the post-migration phase, they integrated Spline directly into EMR Serverless applications.

The lineage workflow consists of the following steps:

  1. As Spark jobs execute, Spline captures detailed metadata about the queries and transformations performed.
  2. The captured metadata is exported as Spline object files to a dedicated S3 bucket.
  3. These Spline objects are processed into column-level lineage objects customized to fit AppsFlyer’s data architecture and requirements.
  4. The processed lineage data is ingested into DataHub, providing a centralized and interactive view of data dependencies.

The following figure is an example of a lineage diagram from DataHub.

Challenges and how AppsFlyer addressed them

AppsFlyer encountered the following challenges:

  • Supporting different EMR Serverless applications – Each EMR Serverless application has its own Spark and Scala version requirements.
  • Diverse operator usage – Teams often use custom or native EMR Serverless operators, making uniform Spline integration challenging.
  • Confirming universal adoption – They need to make sure Spark jobs across multiple accounts use the Spline agent for lineage tracking.

AppsFlyer addressed these challenges with the following solutions:

  • Version-specific Spline agents – AppsFlyer created a dedicated Spline agent for each EMR Serverless application version to match its Spark and Scala versions. For example, EMR Serverless application version 7.0.1 and Spline.7.0.1.
  • Spark defaults integration – They integrated the Spline agent into EMR Serverless application Spark defaults to verify lineage collection for jobs executed on the application—no job-specific modifications needed.
  • Automation for compliance – This process consists of the following steps:
    • Detect a newly created EMR Serverless application across accounts.
    • Verify that Spline is properly defined in the application’s Spark defaults.
    • Send a PagerDuty alert to the dedicated team if misconfigurations are detected.

Example integration with Terraform

To automate Spline integration, AppsFlyer used Terraform and local-exec to define Spark defaults for EMR Serverless applications. With Amazon EMR, you can set unified Spark configuration properties through spark-defaults, which are then applied to Spark jobs.

This configuration makes sure the Spline agent is automatically applied to every Spark job without requiring modifications to the Airflow operator or the job itself.

This robust lineage integration provides the following benefits:

  • Full visibility – Automatic lineage tracking provides detailed insights into data transformations
  • Seamless scalability – Version-specific Spline agents provide compatibility with EMR Serverless applications
  • Proactive monitoring – Automated compliance checks verify that lineage tracking is consistently enabled across accounts
  • Enhanced governance – Ingesting lineage data into DataHub provides traceability, supports audits, and fosters a deeper understanding of data dependencies

By integrating Spline with EMR Serverless applications, AppsFlyer has provided comprehensive and automated lineage tracking, so teams can understand their data pipelines better while meeting compliance requirements. This scalable approach aligns with AppsFlyer’s commitment to maintaining transparency and reliability throughout their data landscape.

Monitoring and observability

When embarking on a large migration, and as a day-to-day best-practice process, monitoring and observability are key parts of being able to run workloads successfully for stability, debugging, and cost.

AppsFlyer’s DataInfra team set several KPIs for monitoring and observability in EMR Serverless:

  • Monitor infrastructure-level metrics and logs:
    • EMR Serverless resource usage, including cost
    • EMR Serverless API usage
  • Monitor Spark application-level metrics and logs:
    • stdout and stderr logs
    • Spark engine metrics
  • Centralized observability over the existing environments, Datadog

Metrics

Using EMR Serverless native metrics, AppsFlyer’s DataInfra team set up several dashboards to support tracking both the migration and the day-to-day usage of EMR Serverless across the company. The following are the main metrics that were monitored:

  • Service quota usage metrics:
    • vCPU usage tracking (ResourceCount with vCPU dimension)
    • API usage tracking (API actual usage vs. API limits)
  • Application status metrics:
    • RunningJobs, SuccessJobs, FailedJobs, PendingJobs, CancelledJobs
  • Resource limits tracking:
    • MaxCPUAllowed vs. CPUAllocated
    • MaxMemoryAllowed vs. MemoryAllocated
    • MaxStorageAllowed vs. StorageAllocated
  • Worker-level metrics:
    • WorkerCpuAllocated vs. WorkerCpuUsed
    • WorkerMemoryAllocated vs. WorkerMemoryUsed
    • WorkerEphemeralStorageAllocated vs. WorkerEphemeralStorageUsed
  • Capacity allocation tracking:
    • Metrics filtered by CapacityAllocationType (PreInitCapacity vs. OnDemandCapacity)
    • ResourceCount
  • Worker type distribution:
    • Metrics filtered by WorkerType (SPARK_DRIVER vs. SPARK_EXECUTORS)
  • Job success rates over time:
    • SuccessJobs vs. FailedJobs ratio
    • SubmitedJobs vs. PendingJobs

The following screenshot shows an example of the tracked metrics.

Logs

For logs management, AppsFlyer’s DataInfra team explored several options:

Streamlining EMR Serverless log shipping to Datadog

Because AppsFlyer decided to keep their logs in an external logging environment, the DataInfra team aimed to reduce the number of components involved in the shipping process and minimize maintenance overhead. Instead of managing a Lambda based log shipper, they developed a custom Spark plugin that seamlessly exports logs from EMR Serverless to Datadog.

Companies already storing logs in Amazon S3 or CloudWatch Logs can take advantage of EMR Serverless native support for those environments. However, for teams needing a direct, real-time integration with Datadog, this approach alleviates the need for extra infrastructure, providing a more efficient and maintainable logging solution.

The custom Spark plugin offers the following capabilities:

  • Automated log export – Streams logs from EMR Serverless to Datadog
  • Fewer extra components – Alleviates the need for Lambda based log shippers
  • Secure API key management – Uses Vault instead of hardcoding credentials
  • Customizable logging – Supports custom Log4j settings and log levels
  • Full integration with Spark – Works on both driver and executor nodes

How the plugin works

In this section, we walk through the components of how the plugin works and provide a pseudocode overview:

  • Driver plugin – LoggerDriverPlugin runs on the Spark driver to configure logging. The plugin fetches EMR job metadata, calls Vault to retrieve the Datadog API key, and configures logging settings.
initialize() {
  if (user provided log4j.xml) {
     Use custom log configuration
  } else {
     Fetch EMR job metadata (application name, job ID, tags)
     Retrieve Datadog API key from Vault
     Apply default logging settings
  }
}
  • Executor plugin – LoggerExecutorPlugin provides consistent logging across executor nodes. It inherits the driver’s log configuration and makes sure the executors use consistent logging
initialize() {
   fetch logging config from Driver
   apply log settings (log4j, log levels)
}
  • Main plugin – LoggerSparkPlugin registers the driver and executor plugins in Spark. It serves as the entry point for Spark and applies custom logging settings dynamically.
function registerPlugin() {
  return (driverPlugin, executorPlugin);
}
loginToVault(role, vaultAddress) {
    create AWS signed request
    authenticate with Vault
    return vault token
}

getDatadogApiKey(vaultToken, secretPath) {
    fetch API key from Vault
    return key
}

Set up the plugin

To set up the plugin, complete the following steps:

  1. Add the following dependencies to your project:
<dependency>
  <groupId>com.AppsFlyer.datacom</groupId>
  <artifactId>emr-serverless-logger-plugin</artifactId>
  <version><!-- insert version here --></version>
</dependency>
  1. Configure the Spark plugin. The following code enables the custom Spark plugin and assigns the Vault role to access the Datadog API key:

--conf "spark.plugins=com.AppsFlyer.datacom.emr.plugin.LoggerSparkPlugin"

--conf "spark.datacom.emr.plugin.vaultAuthRole=your_vault_role"

  1. Use a custom or default Log4j configuration:

--conf "spark.datacom.emr.plugin.location=classpath:my_custom_log4j.xml"

  1. Set the environment variables for different log levels. This adjusts the logging for specific packages.

--conf "spark.emr-serverless.driverEnv.ROOT_LOG_LEVEL=WARN"

--conf "spark.executorEnv.ROOT_LOG_LEVEL=WARN"

--conf "spark.emr-serverless.driverEnv.LOG_LEVEL=DEBUG"

--conf "spark.executorEnv.LOG_LEVEL=DEBUG"

  1. Configure the Vault and Datadog API key and verify secure Datadog API key retrieval.

By adopting this plugin, AppsFlyer was able to significantly simplify log shipping, reducing the number of moving parts while maintaining real-time log visibility in Datadog. This approach provides reliability, security, and ease of maintenance, making it an ideal solution for teams using EMR Serverless with Datadog.

Summary

Through their migration to EMR Serverless, AppsFlyer achieved a significant transformation in team autonomy and operational efficiency. Individual teams now have greater freedom to choose and build their own resources without depending on a central infrastructure team, and can work more independently and innovatively. The minimization of spot interruptions, which were common in their previous self-managed Hadoop clusters, has substantially improved stability and agility in their operations. Thanks to this autonomy and reliability, combined with the automatic scaling capabilities of EMR Serverless, the AppsFlyer teams can focus more on data processing and innovation rather than infrastructure management. The result is a more efficient, flexible, and self-sufficient development environment where teams can better respond to their specific needs while maintaining high performance standards.

Ruli Weisbach, AppsFlyer EVP of R&D, says,

“EMR-Serverless is a game changer for AppsFlyer; we are able to save significantly our cost with remarkably lower management overhead and maximal elasticity.”

If the AppsFlyer approach sparked your interest and you are thinking about implementing a similar solution in your organization, refer to the following resources:

Migrating to EMR Serverless can transform your organization’s data processing capabilities, offering a fully managed, cloud-based experience that automatically scales resources and eases the operational complexity of traditional cluster management, while enabling advanced analytics and machine learning workloads with greater cost-efficiency.


About the authors

Roy Ninio is an AI Platform Lead with deep expertise in scalable data platform and cloud-native architectures. At AppsFlyer, Roy led the design of a high-performance Data Lake handling PB of daily events, driven the adoption of EMR Serverless for dynamic big data processing, and architected lineage and governance systems across platforms.

Avichay Marciano is a Sr. Analytics Solutions Architect at Amazon Web Services. He has over a decade of experience in building large-scale data platforms using Apache Spark, modern data lake architectures, and OpenSearch. He is passionate about data-intensive systems, analytics at scale, and it’s intersection with machine learning.

Eitav Arditti is AWS Senior Solutions Architect with 15 years in AdTech industry, specializing in Serverless, Containers, Platform engineering, and Edge technologies. Designs cost-efficient, large-scale AWS architectures that leverage the cloud-native and edge computing to deliver scalable, reliable solutions for business growth.

Yonatan Dolan is a Principal Analytics Specialist at Amazon Web Services. Yonatan is an Apache Iceberg evangelist, helping customers design scalable, open data lakehouse architectures and adopt modern analytics solutions across industries.
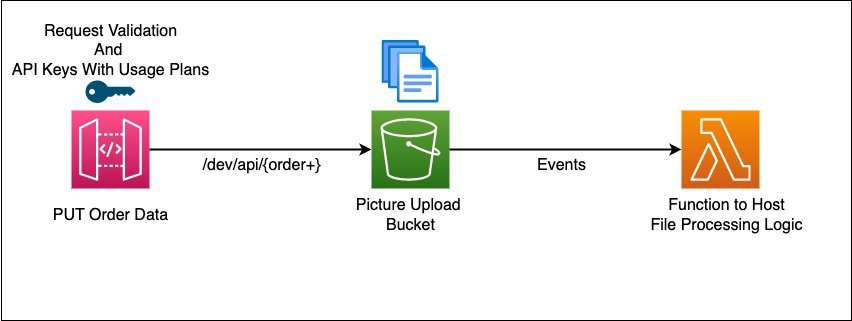
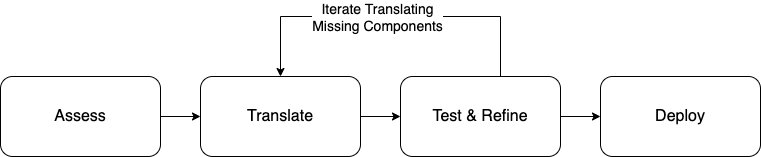
Monitoring network traffic in AWS Lambda functions

Post Syndicated from Anton Aleksandrov original https://aws.amazon.com/blogs/compute/monitoring-network-traffic-in-aws-lambda-functions/

Network monitoring provides essential visibility into cloud application traffic patterns across large organizations. It enables security and compliance teams to detect anomalies and maintain compliance, while allowing development teams to troubleshoot issues, optimize performance, and track costs in multi-tenant software as a service (SaaS) environments. Implementing robust network monitoring allows organizations to effectively manage their security, compliance, and operational requirements while continuously enhancing their applications.

In this post, you will learn methods for network monitoring in AWS Lambda functions and how to apply them to your scenarios.

Overview

Lambda is a secure and highly scalable serverless compute service where each function operates in an isolated execution environment with strict security boundaries. This architecture delivers key advantages, such as enhanced security, automatic compute capacity scaling, and minimal operational overhead. Minimizing infrastructure management allows Lambda to enable organizations to redirect their focus from managing servers to other critical aspects, such as performance optimization and network traffic analysis. In turn, these enable organizations to build more secure and efficient applications.

Lambda network monitoring addresses diverse organizational needs, such as compliance requirements for audit logs and anomaly detection, business needs for traffic metering and customer billing, and development needs for troubleshooting network issues. Traditional agent-based or host-based monitoring methods often aren’t compatible with the strongly isolated, ephemeral execution environment of Lambda, which necessitates alternative approaches to meet these critical requirements.

You can use AWS-native, integrated network monitoring solutions, such as Amazon Virtual Private Cloud (Amazon VPC) Flow Logs, or build your own custom solution, as detailed in this post. Each solution offers distinct capabilities with varying levels of granularity and real-time visibility. When choosing an approach, you must evaluate key factors such as the desired data granularity, operational complexity, latency tolerance, and cost implications.

Using VPC Flow Logs

VPC Flow Logs is the AWS-recommended tool for network activity monitoring. If your scenario necessitates monitoring of the network activity of Lambda functions, then you can attach these functions to a VPC and enable Flow Logs. This captures detailed network traffic data, such as source and destination IPs, ports, protocols, and traffic volume for all traffic flowing through the network interfaces used by your functions.

When you attach your functions to a VPC, the Lambda service automatically creates an Elastic Network Interface (ENI) for functions to communicate with VPC-based resources. By default, VPC-attached functions can only access private resources within the VPC. If you need your functions to communicate with other AWS services, then you should use VPC Endpoints. If your function needs to communicate with the public internet, then you should use an NAT Gateway for egress traffic. The following diagram shows how you can use VPC Flow Logs for Lambda functions.

Flow Logs provide detailed insights into the IP traffic flowing to and from the network interfaces within a VPC, offering valuable data for network audits and activity monitoring. This approach promotes a clear separation of concerns between application and networking layers, with VPC constructs typically managed by a dedicated operations or infrastructure team.

VPC Flow Logs provides a robust network monitoring solution. However, when using it with Lambda functions, you should evaluate the following considerations:

  • It captures ENI-level information. ENIs can be reused across multiple functions, thus it won’t provide per-function or per-invoke granularity.
  • It only logs IP addresses, not DNS names (if capturing DNS names is a requirement for you).
  • It introduces infrastructure management into your serverless applications. You must learn VPC constructs or involve your infrastructure team.
  • Potential added data transfer costs. Go to the pricing for NAT Gateway, VPC Endpoints, and Flow Logs for more details.

The following sections explore Lambda network monitoring methods that can either be augmented with VPC Flow Logs for better granularity or used without attaching your functions to a VPC.

Proxying network traffic

You can configure the Lambda runtime to route egress network traffic through a side-car proxy that runs as a Lambda layer within the Lambda execution environment and logs network activity. The proxy layer should be agnostic to the language runtime. AWS recommends that you use compiled languages such as Rust or Golang for maximum reusability and minimal added latency. The following diagram shows emitting logs from a network proxy layer.

Applying proxy configuration differs across language runtimes. In Python you set proxy_http and proxy_https environment variables. Java uses JVM flags. Node.js doesn’t provide a native way to configure proxy using command line flags or environment variables. Therefore, you need to make code changes, such as configuring a proxy for your AWS SDK or using a third-party open source libraries such as global-agent or Interceptors.

The proxy approach is most suitable if you’re okay with making function code or configuration changes that might vary across runtimes. Furthermore, adding a network proxy server process inside the execution environment consumes resources shared with the function code, which can add network latency.

Refer to the post Enhancing runtime security and governance with the AWS Lambda Runtime API proxy extension for ways to intercept inbound requests/responses between the Lambda Runtime API and Runtime process.

Runtime-agnostic techniques

Following techniques use the fact that the Lambda execution environment is a Linux-based micro-VM. Lambda runtimes operate within a restricted user space that prevents the use of traditional OS-level monitoring tools needing elevated privileges, such as tcpdump, iptables, ptrace, or eBPF. The following techniques are specifically designed to work under these user space constraints, allowing their use without needing elevated privileges.

Reading OS networking layer information from procfs

Use this method when you need to obtain the OS-level information, such as metering transferred bytes, or see all open connections. You can use it to implement tenant chargebacks or detect network traffic pattern changes. The method is based on the proc pseudo-filesystem (also known as procfs) available in Linux OS, which provides an interface to kernel data and allows you to read OS-level information. For example, /proc/cpuinfo and /proc/meminfo pseudo-files provide information about current CPU and memory usage, while /proc/net/* provides you with network layer information. Reading /proc/net/tcp and /proc/net/udp gives you a list of active TCP/UDP connections, such as remote IP addresses and ports. Reading /proc/net/dev provides the list of network devices with detailed usage statistics, such as bytes transferred and received.

“The procfs method provides a simple but powerful way to collect critical network telemetry data from Lambda functions, such as up-to-date network statistics and file descriptor counts, which enables us to monitor outbound connections from Lambda functions. Better yet, it enables us to support multiple Lambda runtimes with a single implementation in our Rust-based, next-generation Lambda Extension”—AJ Stuyvenberg, Staff Engineer at Datadog.

The sample project provides the LambdaNetworkMonitor-Procfs stack to show this technique. For every invocation, the function reads /proc/net/dev, and sends network statistics to log and Amazon CloudWatch Metrics, as shown in the following figure.

Reading the /proc/net/dev pseudo-file is a simple and effective way to monitor Lambda functions networking without adding latency. However, it doesn’t capture DNS names and the IP addresses to which they resolve.

Intercepting network-related libc calls

Low-level network operations in Linux, such as DNS lookup and connection creation, are managed by the C Standard Library (libc). You can intercept libc function calls made by Lambda runtimes to monitor network traffic at the OS level. This is a significantly more advanced and complex mechanism, enabling visibility into OS-level activities, as shown in the following figure.

Intercepting libc function calls, such as getaddrinfo (DNS lookup) and connect, allows you to log details such as DNS name, IP addresses, ports, and protocols at a granular level, as shown in the following figure. This method allows you to capture comprehensive information about DNS queries and initiated network connections. It can provide precise per-function and per-invoke network monitoring, such as hostnames and IP addresses.

The following is a simplified flow:

  1. A function sends a request to example.com.
  2. The runtime calls libc getaddrinfo to resolve the DNS name.
  3. You intercept this call, log the DNS name, and forward the call to the original libc getaddrinfo.
  4. The original libc getaddrinfo returns resolved IP addresses. You log them and return to the runtime.
  5. The runtime calls libc connect method to create a new connection.
  6. You intercept this call, log the IP address, forward the call to the original libc connect, and so on.

To implement this technique, you need to use a language that compiles to a shared object (.so) file. To implement libc method signatures you should use a language such as C, C++, or Rust. The following sample code uses Rust for its strong safety guarantees and implements overriding the getaddrinfo libc function (DNS lookup).

pub extern "C" fn getaddrinfo(
    node: *const c_char,
    service: *const c_char,
    hints: *const addrinfo,
    res: *mut *mut addrinfo,
) -> c_int {
    let printable_node = format!("{}", PrintableCString::from(node));
    let printable_service = format!("{}", PrintableCString::from(service));

    log::debug!("> getaddrinfo node={printable_node} service={printable_service}");

    LIBC_GETADDRINFO(node, service, hints, res)
}

The following should be considered:

  • The method signature fully matches the libc function signature of the same name.
  • The node and service arguments would commonly be DNS name and port.
  • At the end, the function invokes the real libc getaddrinfo and returns the result.

When compiled to an .so file, you must package it as a Lambda layer, attach the layer to your functions, and configure the execution environment to use it through the Linux dynamic linker capability called preloading. Set the LD_PRELOAD environment variable to point to your .so file to instruct the OS to preload it before it loads any other library, such as libc. You can configure this either as a function environment variable or through a wrapper script, as shown in the following figure.

#!/bin/sh
echo "running wrapper..."
args=("$@")
export LD_PRELOAD=/opt/liblambda_network_monitor.so
exec "${args[@]}"

This technique allows you to get detailed connection-level monitoring such as DNS lookups, resolved IP addresses, ports, protocols, and count bytes transferred. Depending on your requirements, it can be adapted to track further network-related information as needed.

The sample project provides the LambdaNetworkMonitor-LdPreload stack to show this technique, as shown in the following figure. For every invocation, the function prints intercepted libc functions, DNS names, and connection IP addresses.

Considerations

  • OS-level techniques necessitate strong understanding of Linux fundamentals and careful implementation. AWS recommends that you closely evaluate which methods to use and keep your solution minimally invasive.
  • LD_PRELOAD is an advanced low-level technique that allows you to override libc methods and OS behavior. Incorrectly implemented hooks could lead to undefined behavior and crashes. Make sure your code is robust to recursion and thread-safe. Test it thoroughly in a controlled environment before using it in production.
  • The LD_PRELOAD technique relies on dynamic linking. It works with dynamically linked runtimes such as Node.js, Python, and Java. It doesn’t work with runtimes that use static linking, such as Golang.
  • When using runtime-dependent functionality, consider using Lambda runtime update controls to make sure that runtimes are only updated when the next function update occurs.
  • Always install layers from trusted sources only. Use infrastructure as code (IaC) tools to attach and audit layer configurations, such as AWS Identity and Access Management (IAM) permissions.

Conclusion

Monitoring network traffic in Lambda functions is a common requirement for many organizations. In case you need to audit IP-level network logs, AWS recommends that you to attach your functions to a VPC and use Flow Logs. If you need per-function or per-invoke granularity, then you can augment it with techniques described in this post.

These techniques provide valuable insights for debugging, auditing, and monitoring, but they also necessitate a solid understanding of Linux fundamentals and careful implementation. They offer a practical solution for organizations that need Lambda network monitoring, allowing them to troubleshoot issues and maintain compliance.

To learn more about Serverless architectures and asynchronous Lambda invocation patterns, go to Serverless Land.

AWS Lambda introduces tiered pricing for Amazon CloudWatch logs and additional logging destinations

Post Syndicated from Shridhar Pandey original https://aws.amazon.com/blogs/compute/aws-lambda-introduces-tiered-pricing-for-amazon-cloudwatch-logs-and-additional-logging-destinations/

Effective logging is an important part of an observability strategy when building serverless applications using AWS Lambda.

Lambda automatically captures and sends logs to Amazon CloudWatch Logs. This allows you to focus on building application logic rather than setting up logging infrastructure and allows operators to troubleshoot failures and performance issues more easily.

On May 1st, 2025, AWS announced changes to Lambda logging, which can reduce Lambda CloudWatch logging costs and make it easier and more cost-effective to use a wider range of monitoring tools. Lambda logs are now available at volume-based tiered pricing when using CloudWatch Logs Standard and Infrequent Access log classes. When generating Lambda logs at scale, you can expect an immediate cost reduction under this new pricing model. Lambda also now supports Amazon S3 and Amazon Data Firehose as additional destinations for Lambda logs, in addition to CloudWatch Logs. Lambda logs sent to S3 and Firehose are also available at volume-based tiered pricing.

This blog post covers some recent Lambda logging enhancements and describes how this change delivers a simpler, more cost-effective logging experience for Lambda.

Overview

Logging provides developers and operators with valuable data for debugging and troubleshooting application behavior, performance issues, and potential failures. It becomes even more important for serverless applications built using Lambda because of the ephemeral and stateless nature of the Lambda execution environment. Lambda’s built-in integration with CloudWatch Logs ensures that logs for every function invocation are readily available for analysis. The captured log data includes application logs generated by your Lambda function code and system logs generated by the Lambda service while running your function code. CloudWatch Logs allows you to search, filter, and analyze log data to troubleshoot issues, track metrics, and set up alerts.

Logging requirements evolve as serverless applications grow in complexity and scale, sometimes spanning hundreds or thousands of Lambda functions which generate substantial log volumes. Organizations need sophisticated logging solutions that can handle this scale while remaining cost-effective. Some scenarios—such as monitoring critical business transactions—demand real-time log analysis, while others focus on after-the-fact forensic analysis. Debug logs from development and staging environments often need high granularity, whereas you may want lower verbosity in production logs to improve the signal-to-noise ratio.

Recent Lambda logging enhancements

In recent years, Lambda and CloudWatch Logs have expanded Lambda’s logging capabilities to meet the evolving needs of serverless applications. These capabilities provide deeper insights, greater control, and more cost-effective solutions to capture, process, and consume logs to enhancing the serverless observability experience. Lambda advanced logging controls gives developers control over log generation and content. These controls allow you to capture Lambda logs in JSON structured format. You don’t have to use logging libraries and customize log levels (INFO, DEBUG, WARN, ERROR) separately for application and system logs. This helps reduce logging costs by ensuring only necessary logs are generated while maintaining appropriate visibility across different environments. For example, you can set verbose DEBUG level logging in development environments while limiting production logging to ERROR level to improve the signal-to-noise ratio and control costs.

The Infrequent Access log class for CloudWatch Logs introduced a cost-effective solution for logs that need retention but are accessed less frequently. Infrequent Access is 50% lower per GB ingestion price than the Standard log class This tailored set of capabilities allows you to reduce your logging costs while maintaining access to historical data for compliance, audit purposes, or forensic analysis.

CloudWatch Logs Live Tail is an interactive, real-time log streaming and analytics capability. Live Tail streamlines debugging and monitoring workflows; it allows you to observe log output as functions execute without navigating away from the Lambda console. This makes it easier to identify and diagnose issues during development and troubleshooting. Logs Live Tail is also available in Visual Code IDE.

Tiered pricing for Lambda logs in CloudWatch Logs

Starting today, Lambda logs sent to CloudWatch Logs are classed as Vended Logs, which are logs from specific AWS services that are available at volume tiered pricing. This replaces the previous flat rate model when using CloudWatch Logs Standard log class. For example, in the US East (N. Virginia) AWS Region, you were charged at $0.50 per GB when using Standard log class for your Lambda logs. Under the new pricing model, you are charged for sending your Lambda logs to CloudWatch Logs starting at $0.50 per GB for initial usage. As log volume increases, the price per GB automatically decreases through multiple tiers, reaching rates as low as $0.05 per GB in the lowest tier. This pricing change applies automatically to all Lambda logs sent to CloudWatch Logs, requiring no code or configuration changes from you.

Data Ingested CloudWatch Logs Standard CloudWatch Logs Infrequent Access
First 10 TB per month $0.50 per GB $0.25 per GB
Next 20 TB per month $0.25 per GB $0.15 per GB
Next 20 TB per month $0.10 per GB $0.075 per GB
Over 50 TB per month $0.05 per GB $0.05 per GB

Table 1: Tiered pricing for Lambda logs in CloudWatch Logs in US East (N. Virginia) Region

When generating Lambda logs at scale, you will see an immediate cost reduction under this new pricing model. For example, if you generate 60 TB of Lambda logs monthly in CloudWatch Logs, costs would decrease by 58% (from $30,000 to $12,500). The pricing tiers scale with your logging volume, ensuring that cost benefits increase as your application grows. This allows you to maintain comprehensive logging practices that previously may have been cost-prohibitive. Vended logs tiered pricing is applied on all vended logs ingested to CloudWatch and not tiered per service.

When ingesting other vended logs, such as Amazon Virtual Private Cloud flow logs and Amazon Route 53 resolver query logs, you will see larger discounts as the tiering is applied at a consolidated log ingestion volume.

New Lambda logging destinations: Amazon S3 and Amazon Data Firehose

Starting today, Lambda also supports Amazon S3 and Amazon Data Firehose as destinations for Lambda logs, in addition to CloudWatch Logs. When using S3 or Firehose as a destination, logging costs start at $0.25 per GB. The tiered pricing also applies, with rates reducing to as low as $0.05 per GB in the lowest tier. This tiering is also applied at a consolidated log ingestion volume.

Data Ingested Delivery Cost to Amazon S3 Delivery Cost to Amazon Data Firehose
First 10TB per month $0.25 per GB $0.25 per GB
Next 20TB per month $0.15 per GB $0.15 per GB
Next 20TB per month $0.075 per GB $0.075 per GB
Over 50TB per month $0.05 per GB $0.05 per GB

Table 2:Tiered pricing for Lambda logs delivery to Amazon S3 and Amazon Data Firehose in US East (N. Virginia) Region

Direct delivery of Lambda logs to S3 provides enhanced flexibility in log management. Support for Firehose streamlines Lambda log delivery to additional destinations such as Amazon OpenSearch Service, HTTP endpoints, and third-party observability providers. This matches the established log delivery pattern used with other AWS compute services such as Amazon Elastic Container Service (Amazon ECS) and Amazon Elastic Compute Cloud (Amazon EC2).

This new capability provides significant cost benefits and streamlines log delivery to additional logging destinations, making it easier to use a wider range of monitoring tools (including CloudWatch) when building serverless applications using Lambda.

New Lambda logging destinations in action

All new and existing Lambda functions have CloudWatch Logs as the default logging destination, with S3 and Firehose as alternative choices. When you select S3 or Firehose as your logging destination, Lambda sends logs to the selected destination via a new CloudWatch Logs Delivery log class. This log class enables efficient routing but doesn’t support CloudWatch Logs Standard log class features, such as Logs Insights and Live Tail.

To set up S3 or Firehose as the destination for your Lambda logs in the Lambda console:

  1. Navigate to the Lambda console, and select or create a function to set up an S3 or Firehose logging destination.
  2. In the Configuration tab, select Monitoring and operations tools on the left pane.
  3. Select Edit in the Logging configuration. This opens the Edit logging configuration page.

    Figure 1. Edit logging configuration in Lambda console

    Figure 1. Edit logging configuration in Lambda console

  4. In the Log destination section, select Amazon S3 or Amazon Data Firehose. Amazon CloudWatch Logs is the default selection.

    Figure 2. Select log destination in the Edit logging configuration page

    Figure 2. Select log destination in the Edit logging configuration page

  5. Under CloudWatch delivery log group, choose Create new log group or Existing log group.
  6. To create a new delivery log group to send logs to S3, enter a log group name and specify the destination S3 bucket. Provide an AWS Identity and Access Management (IAM) role for CloudWatch Logs to deliver logs to S3.
    Follow similar steps to send logs to a Firehose stream.

    Figure 3. Create new CloudWatch delivery log group for S3

    Figure 3. Create new CloudWatch delivery log group for S3

  7. To use an existing delivery log group, select one from the Delivery log group. The selected delivery log group must have a configured destination (S3 or Firehose) and match the destination you selected.

    Figure 4. Select existing CloudWatch delivery log group for Firehose

    Figure 4. Select existing CloudWatch delivery log group for Firehose

Advanced logging controls are also available for S3 and Firehose destinations. These controls include JSON structured format selection and log level filters for both application and system logs. This gives you enhanced log management controls for easier search, filter, and analysis. You can also use AWS Command Line Interface (AWS CLI) and infrastructure as code (IaC) tools such as AWS CloudFormation and AWS Cloud Development Kit (AWS CDK) to set up Lambda logs delivery to S3 and Firehose.

Best practices

To get the most out of the changes announced today, ensure that your logging strategy is closely aligned with the requirements of your workload. For example, consider sending critical production logs to CloudWatch Logs to take advantage of its advanced real-time analytics and alerting features. You now automatically benefit from volume-based discounts through tiered pricing in CloudWatch Logs for high-volume logging scenarios. For logs that need long-term retention for historical analysis, you can use S3’s storage classes to further reduce costs. When using your existing or third-party monitoring tools, direct integration through Firehose eliminates the need for custom forwarding solutions and associated costs.

Logging cost optimization extends beyond destination selection. Monitor log volumes regularly to understand the impact of pricing tiers. Implement appropriate retention policies to prevent unnecessary storage of old logs and log sampling for high-volume debug logs. Consider using different logging strategies across development, staging, and production environments to balance observability needs with cost efficiency.

Conclusion

Tiered pricing for Lambda logs in CloudWatch Logs and support for S3 and Firehose as additional logging destinations improves Lambda application observability. You can now manage logging costs at scale and expand Lambda monitoring solutions through cost-effective, easy-to-configure integrations. Whether you’re building new serverless applications or optimizing existing ones, these enhancements help you implement comprehensive logging strategies that scale cost-effectively with your workload.

The new features announced today are available in all commercial AWS Regions where Lambda and CloudWatch Logs are available. Support for configuring log delivery to S3 and Firehose in the Lambda console is available in US East (Ohio), US East (N. Virginia), US West (Oregon), and Europe (Ireland) Regions, with additional Regions coming soon. Review the Lambda documentation and CloudWatch Logs documentation to learn more about these features and how to use them. Review the CloudWatch pricing page to learn more about how these features are priced.

For more serverless learning resources, visit Serverless Land.

Integrating aggregators and Quick Service Restaurants with AWS serverless architectures

Post Syndicated from Mike Gomez original https://aws.amazon.com/blogs/compute/integrating-aggregators-and-quick-service-restaurants-with-aws-serverless-architectures/

In this post, you learn how to use AWS serverless technologies, such as Amazon EventBridge and AWS Lambda, to build an integration between Quick Service Restaurants (QSRs) and online ordering and food delivery aggregators. These aggregators have taken off as an option to QSRs to expand their consumer base, enabling them with delivery options to help grow their businesses.

QSR overview

QSRs prioritize speedy and convenient service, offering a streamlined menu. To meet evolving consumer expectations, QSRs can use API integrations with third-party aggregators. This technological synergy enables QSRs to expand their capabilities, introducing diverse payment methods and incorporating delivery services. These features have become standard in this restaurant segment.

Behind the scenes, the APIs are used to orchestrate the interaction between the aggregator and the QSR while having a consistent ordering and delivery experience.

QSR business objectives are:

  • Providing consistent ordering and delivery experiences
  • Offering personalized menu items
  • Retaining repeat customers
  • Reducing third-party delivery cancellation due to lack of delivery personalization options

This post starts with a simple architecture and adds components to solve architectural challenges.

Architecture

As a solutions architect, you’ve been approached by a thriving local restaurant business seeking technological solutions to fuel their expansion. Your task is to design an optimal integration architecture that aligns with their technical requirements, streamlines operations, and enhances customer experience.

At the core of this integration is Amazon API Gateway, which accepts the incoming orders from various delivery aggregators. The API Gateway becomes the front door, connecting the QSRs with the end customers for a streamlined and dynamic order processing system.

Driving the backend of this integration are Lambda functions. These functions validate orders and securely communicate with delivery aggregators. Lambda functions can scale dynamically based on-demand, and make sure of optimal resource usage and cost-effectiveness.

Order placement workflow

The following steps outline the serverless integration between API Gateway and Lambda functions, as shown in the following figure:

  • Customers can place orders either through food delivery aggregators or the business’s own ordering system.
  • The order request is sent to API Gateway.

This architecture works for small and simple integrations. To scale this architecture for high traffic, use asynchronous integration to reduce the coupling between API and Lambda function.

Order routing workflow

The following steps outline a serverless integration where API Gateway connects to Lambda functions through Amazon EventBridge as the event routing service, as shown in the following figure:

  1. API Gateway receives the order request.
  2. The API Gateway routes the customer’s order request to an EventBridge bus for processing.

EventBridge routes events (for example order status changes) to Lambda functions, making sure of resiliency during service disruptions. This eliminates manual error handling and keeps QSRs and aggregators synchronized.

EventBridge delivers the following essential capabilities:

  • EventBridge receives events triggered by various actions, such as new orders or menu updates.
  • It routes events to the relevant Lambda functions, initiating the appropriate actions.
  • EventBridge supports event replay, allowing recovery from Lambda deployment issues or function failures. This feature enables business continuity by storing events during service disruptions and automatically resuming processing when the system stabilizes.

To maintain order history and enable fast data retrieval, the system needs a highly performant database. Amazon DynamoDB, a serverless NoSQL database service, meets these requirements by efficiently storing and managing order information and metadata. The order processing Lambda function interacts with DynamoDB to persist order details. This approach enables asynchronous processing of the stored data by other backend processes. The database solution provides the scalability and responsiveness needed to handle growing order volumes while maintaining consistent performance, separating order intake from subsequent processing steps.

Order processing workflow

The following steps outline the order processing workflow, as shown in the following figure:

  • The order processing Lambda function validates the order and updates the DynamoDB database with the new order details.
  • The function publishes error events to EventBridge, enabling downstream processing for error handling and retry logic. These events can trigger more Lambda functions designed to manage specific error scenarios and recovery processes.

EventBridge implementation patterns: single or dual bus approaches

EventBridge offers multiple approaches for event bus topology. Architects can choose to either use a single event bus with distinct event patterns based on order status or implement a multi-bus strategy.

The single-bus approach uses one event bus for all events with routing rule patterns based on order status. For example, rules would match specific statuses (for example “new” or “processed”) to trigger appropriate Lambda functions. Although it is architecturally simple, it needs careful management of the event schema to avoid potential errors. However, a single-bus approach requires careful handling to prevent recursive processing, where messages trigger additional messages in an endless loop.

Alternatively, the multi-bus method, separating order placement and processing across different buses, effectively prevents loops and recursion issues. This approach provides better separation of transactions, albeit with a slightly more complex setup.

EventBridge can directly target external services using the API destination option, eliminating the need for Lambda functions for third party integrations.

Orchestrating order processing

In complex order processing systems for QSRs, managing multiple interdependent Lambda functions can become challenging, potentially leading to intricate code and difficult-to-maintain architectures. To address this, AWS Step Functions can be introduced as an orchestration layer.

Step Functions acts as a central coordinator for the business logic needed in QSR order flows. This service manages the progression of activities in the order processing workflow, thereby efficiently coordinating tasks such as kitchen preparation and delivery logistics. Defining and managing complex workflows allows Step Functions to optimize the overall efficiency of QSR operations, providing a structured and adaptable solution. This orchestration enhances the restaurant’s ability to handle dynamic processing, achieving a smooth and responsive integration with delivery services while streamlining the underlying architecture.

The following steps outline the orchestration of order processing, as shown in the following figure:

  • Order processing trigger respective Lambda function, which updates the order data in the DynamoDB database.
  • The updated order is made available for subsequent Lambda functions that process more business logic being performed by further Lambda functions.

In a multi-bus EventBridge architecture, the process flows are as follows:

  1. The first EventBridge bus receives the initial order event and routes it to a Step Functions workflow.
  2. The Step Functions workflow orchestrates the order processing, coordinating various tasks and checks.
  3. Upon completion, the Step Functions workflow emits an event with the processing results to the second EventBridge bus.
  4. Based on the output from the Step Function workflow, this second bus contains a rule that triggers the Aggregator API as an API destination.

User engagement workflow

When a customer places an order, there must be a way to confirm or notify them when the order is ready. For this purpose, you can use AWS End User Messaging services to push notifications for order completion and new offers to customers.

Analyzing customer data and individual preferences allows Amazon Personalize to be used to present personalized recommendations and promotions.

Amazon Personalize can analyze historical order data to enhance the user experience through personalized recommendations, such as optimal delivery times, preferred menu items, and tailored promotions based on individual ordering patterns.

Conclusion

This post showed how to use AWS serverless services to build a platform for your order processing without worrying about managing underlying infrastructure. The serverless services included were Amazon API Gateway, AWS Lambda, Amazon EventBridge, AWS Step Functions, AWS End User Messaging, and Amazon Personalize.

This post is a brief introduction to event-driven architectures focused on integrations of internal ordering systems with delivery aggregators and third-party ordering platforms. This can help expand the user base, and it has been a key factor in the growth of many QSRs. Making the ordering, take-out, and delivery experience more efficient translates to revenue growth, reduction of order abandonment, as well as increased recurrent customer retention and brand loyalty.

For more serverless learning resources, visit Serverless Land. To find more patterns, go directly to the Serverless Patterns Collection.

Accelerate data pipeline creation with the new visual interface in Amazon OpenSearch Ingestion

Post Syndicated from Samuel Selvan original https://aws.amazon.com/blogs/big-data/accelerate-data-pipeline-creation-with-the-new-visual-interface-in-amazon-opensearch-ingestion/

Amazon OpenSearch Ingestion is a fully managed serverless pipeline that allows you to ingest, filter, transform, enrich, and route data to an Amazon OpenSearch Service domain or Amazon OpenSearch Serverless collection. OpenSearch Ingestion is capable of ingesting data from a wide variety of sources and has a rich ecosystem of built-in processors to take care of your most complex data transformation needs.

Today, we’re launching a new visual interface for OpenSearch Ingestion that makes it simple to create and manage your data pipelines from the AWS Management Console. With this new feature, you can build pipelines in minutes without writing complex configurations manually.

The new visual interface brings three key improvements to help streamline your workflow:

  • A guided visual workflow that walks you through pipeline creation
  • Automatic permission setup that eliminates manual AWS Identity and Access Management (IAM) policy management
  • Real-time validation checks that help catch issues early

These enhancements make it straightforward to ingest, transform, enrich, and route your data, whether you’re setting up your first pipeline or architecting sophisticated data workflows with multiple transformations and sinks.

In this post, we walk through how these new features work and how you can use them to accelerate your data ingestion projects.

Automatic discovery

Before the visual interface, creating an OpenSearch Ingestion pipeline started with selecting a blueprint that provided a template with placeholders for sources and sinks. You would then need to manually modify this template to match your specific requirements.

The new visual interface improves this process by automatically discovering your sources and sinks as you build. Instead of modifying template code, you can simply select from available resources on the dropdown menus and watch your pipeline configuration build in real time.

This automatic discovery feature eliminates the need to switch between different service consoles to find your source and sink details. Previously, you had to navigate to services like Amazon Simple Storage Service (Amazon S3) or Amazon DynamoDB to copy resource details and Amazon Resource Name (ARN) values, then switch back to enter them into your template. This keeps you focused on your pipeline design, streamlining the entire creation process.

Automated IAM role management

With automatic permission creation, you no longer need to manually create IAM policies for your pipelines and the components involved. With the new UI, you can now create a unified IAM role automatically, granting the necessary permissions for all the components in your pipeline. This significantly reduces the complexity of security management and minimizes the risk of permission-related errors. You can also still use your existing roles if you have them defined already.

Real-time validation

The new interface introduces real-time validation capabilities that go far beyond basic syntax checking. Whereas previous versions only validated keyword syntax, the new interface executes your processor chain in real time, catching both configuration and runtime errors as you build. As you construct your pipeline, the interface continuously validates your entire configuration, helping you identify and resolve potential issues like processor misconfigurations, data type mismatches, or transformation errors before deployment. This proactive, execution-based validation approach helps make sure your pipelines work as intended from the start, alleviating the need to wait until runtime to discover processing chain issues.

Now that we’ve covered the key features, let’s walk through the process of creating a pipeline using the new interface.

Create a pipeline in OpenSearch Ingestion

Getting started with the visual interface is straightforward — you can choose a blueprint as your pipeline foundation or start with a clean slate from a blank template. The interface then guides you through each step, using intelligent resource discovery and automatic population features to simplify the entire creation process. For this post, we use the “Zero-ETL with DynamoDB” blueprint.

The visual interface streamlines source configuration by presenting your DynamoDB tables on an easy-to-navigate dropdown menu. After you select a table, the interface handles all the technical details, including automatically retrieving and configuring the ARN. This same functionality extends to Amazon S3 export configuration, where you can choose Browse S3 to select your bucket and folders directly within the pipeline creation workflow.

After your source is configured, you can enhance your pipeline with processors to transform your data. The processor configuration panel starts with a search field where you can find and select the processor you need. You can choose Add to include processors also then arrange them in the desired order. This flexibility allows you to build complex data transformation workflows by combining different processors in the sequence you need.

If there are any issues, such as missing required fields, the interface displays clear error messages, allowing you to address problems before moving forward. This validation at each step makes sure your pipeline is properly configured before deployment.

The following screen capture shows an example of the visual interface.

The interface’s real-time validation capabilities extend to processor configuration, helping you identify and resolve potential issues before they impact your pipeline. Each processor’s configuration is validated as you build your pipeline, with clear error messages guiding you toward proper setup. This proactive validation approach makes sure your data transformation logic is sound before moving to the next stage of pipeline creation.

The sink configuration panel offers flexibility in choosing your OpenSearch destination. You can select between a managed cluster or serverless option, depending on your specific needs. For added convenience, we’ve integrated the ability to create a new OpenSearch domain directly from this interface, streamlining the end-to-end pipeline setup process.

The sink configuration provides options for both dynamic and custom mapping. Dynamic mapping automatically handles data type detection and mapping creation, whereas custom mapping gives you precise control over your data structure. To maintain data reliability, you can enable a dead-letter queue (DLQ)—a holding area for messages that couldn’t be processed successfully—to capture and manage any failed events.

As you make choices in the visual interface, the corresponding YAML/JSON configuration updates in real time. This immediate feedback helps you understand how your selections translate into technical configurations, from index naming to mapping options and advanced settings like flush timeout and document versioning.

Security configuration is now seamless with automated IAM role management. The interface intelligently handles the creation and management of permissions across all pipeline components. You can either create a new service role or use an existing one, and the interface automatically generates a unified IAM role that provides the precise permissions needed across pipeline components—from your source to Amazon S3 components needed for the DLQ and OpenSearch/Amazon S3 sinks. This automation not only saves time but also reduces the risk of permission-related errors that could occur when managing access controls across multiple resources. The following screen capture shows an example.

By consolidating resource selection into a single interface, we’ve eliminated the need to navigate between multiple AWS services. This saves time and reduces the potential for errors that could occur when manually copying resource identifiers. Once a pipeline is created using the visual interface, you can also edit a pipeline using the same visual interface to quickly alter pipeline configuration.

Conclusion

The new visual interface for OpenSearch Ingestion introduces guided visual workflows that simplify pipeline creation, automatic discovery of resources, automated IAM role management, real-time validation, and dynamic configuration previews. These enhancements collectively streamline the pipeline creation process, reduce the potential for errors, and provide a more intuitive experience for users of all skill levels.

Ready to get started? Visit the OpenSearch Service console today and begin building your first visual pipeline. With this new interface, you can transform your data ingestion workflows and unlock new insights from your data more quickly and efficiently than ever before.


About the authors

Sam Selvan is a Principal Specialist Solution Architect with Amazon OpenSearch Service.

Jagadish Kumar (Jag) is a Senior Specialist Solutions Architect at AWS focused on Amazon OpenSearch Service. He is deeply passionate about Data Architecture and helps customers build analytics solutions at scale on AWS.