I joined Amazon Web Services (AWS) as a principal security engineer 3 years ago and my first project was leading security for PL/Rust on Amazon Relational Database Service (Amazon RDS). This is an extension that lets you write custom functions for PostgreSQL in Rust, which are then compiled to native machine code. These functions can be quite performant and offer a lot of advantages to customers.
From my perspective as a security engineer, “compiled to native machine code” was a flashing neon sign that said, “Start work here” with a big arrow pointing to the Rust toolchain and that’s exactly where I dove in.
The pieces of the system
postgrestd is the Rust standard library at the heart of PL/Rust. The design of this library includes prevention for database escapes. However, at the time, it was fairly new and hadn’t yet been hardened to the realities of production environments at scale. Adding to the challenge, PL/Rust compiles extensions on the database instance itself. This requires a full toolchain to be available locally.
If the extension has a full toolchain available, the potential risk increases. Poorly constructed extensions can cause issues for the database or the host instances. Attackers can use a variety of techniques to try to get around the security controls put in place or break the write xor execute (W^X) model for the container.To support PL/Rust and provide this functionality to customers safely, we needed to add a series of mitigations to address these new risks.
Challenging our approach
Behind the scenes in AWS, we obsess over how we operate our systems. We focus on automation and resilience to help make sure that we meet our commitment to our customers. We’ve learned time and time again that simpler is often a better choice. Operating at scale is complicated enough, don’t add to the problem!
SELinux was—and continues to be—a long debated option for a number of solutions. For those unfamiliar, SELinux is a set of kernel features and tools that enforce mandatory access control on Linux subsystems. Using SELinux policies, you can be extremely specific about what is allowed on a system. You can mandate that a process cannot write to a specific file, even if the ownership of that process permits that actor.
In simpler terms, SELinux mandatory access control is another layer of protection that can be added to the existing authorization system. If a process has permissions to a file, SELinux can block those permissions if a policy is configured for that action. It’s a deterministic way of making sure that specific actions don’t happen.
This approach can greatly increase the security of the operating system. The trade off? Reduced flexibility when it comes to operating that system and the effort required to configure mandatory access control to meet your security requirements. Like any security control, you need to understand the benefit and compare it to the potential downside.
When it came to the PL/Rust case, the benefits of SELinux outweighed the downside. This functionality would allow us to provide the ability to enable PL/Rust to customers in a safe and secure manner.
As simple as it is to write that out, the reality was representative of the culture at AWS. As a brand new team member, I brought the idea up and our senior leaders took the time to listen. The discussions were tough as we all deeply questioned the idea and its implementation. One aspect of our culture is that we try to peek around corners and try to anticipate issues before they occur.
This type of discussion and push back on ideas helps make sure that we’re making the right call for our customers. It’s not always easy, but it is worth it. As a result of these discussions, we agreed to try the SELinux approach for this feature.
Building a complete solution
Our builders and operators built the SELinux environment, and we created appropriate policies for enforcement. This was an important first step, but not the most interesting part of the story.
We configured the mandatory access control policies to send denial messages to our telemetry systems. AWS systems generate a lot of telemetry and we regularly use this information to learn about the state of our systems and improve how we operate and design them.
Using this infrastructure, we started to build a process that would allow us to respond and investigate the denial messages generated. Working with our blue team, we developed playbooks for incident response specifically for our Amazon RDS team. We started running game days every quarter, where we have our red team stage exploits on the system and we would respond.
Afterwards, all our teams came together to measure and analyze the responses. We worked to identify bottlenecks or areas where we could improve. This regular effort helped to mature our response quickly.
At this point, we had a strong solution to reduce the risks of enabling PL/Rust, deep monitoring of our systems, and a well-tested incident response process that helped improve the entire setup.
In action
With the feature in production, we use our monitoring system to automatically cut a high severity ticket to our service team for every SELinux denial message. This level of follow-up helps us make sure that the controls are working as expected and it provides valuable insights in the reality of potential risks to the system.
This process for tracking and investigating possible issues helps our team make sure that we’re providing the level of service our customers expect. As PostgreSQL or Rust releases new features, or when customers have a new data analysis need, we want our security controls to support that work, not block it needlessly.
The feedback loop we’ve created with the investigation of the mandatory access control log messages helps our team to stay aware of what activities are being attempted in the environment. This not only helps catch issues that could affect intended uses, but also acts as an intrusion detection system.
An example of this use recently became public. In October, our team was assigned a high severity ticket that was automatically generated based on an SELinux denial message.
After a quick check to make sure that we hadn’t failed to update our monitoring criteria after recent changes to PL/Rust, our red team, blue team, and AWS security sprang into action. Remember, this activity was kicked off in response to unsuccessful access attempts! It was initiated by a message from the system letting us know it had stopped an activity, but—as is our practice—we wanted to understand what had been attempted.
We verified that the SELinux policy was correctly enforced and had blocked the activity in question. That taken care of, we continued to chase down this issue. As an aside, you might be asking yourself why we would continue to work on this case. That’s a valid question, and the answer is straightforward: we’re constantly looking to see if we can improve our systems to be more effective or more efficient.
Finding the root cause of the signal and learning more about it helps to tune our approach. Depending on the situation, we might be able to avoid a potential risk entirely and reduce the volume of alerts. Or we might see an opportunity to roll out a new feature that helps customers achieve their goals without reducing the security of the system.
In this case, our investigation determined that the detected activity was initiated by the research team at Varonis Threat Labs. We reached out to them and let them know that we had detected their activity, offering to work with them because collaboration with the research community often leads to security improvements that benefit our customers.
In this situation, the initial block and detection validated our security approach. Our policies worked as expected and prevented the activity the researchers were attempting to complete.
The research team, Tal Peleg and Coby Abrams at Varonis Threat Labs, recently spoke about this case at BlackHat 2025. They’ve published the details of their work on the Varonis blog.
As a security engineer, this is quite validating. While we test and validate the controls we put in place, to see a concrete example of how that work can benefit our customers is deeply rewarding.
If you have feedback about this post, submit comments in the Comments section below.
Today, I’m happy to share recent Magic Quadrant reports that named AWS as a Leader in more cloud technology markets: Cloud-Native Application Platforms (aka Cloud Application Platforms) and Container Management.
2025 Gartner Magic Quadrant for Cloud-Native Application Platforms AWS has been named a Leader in the Gartner Magic Quadrant for Cloud-Native Application Platforms for 2 consecutive years. AWS was positioned highest on “Ability to Execute”. Gartner defines cloud-native application platforms as those that provide managed application runtime environments for applications and integrated capabilities to manage the lifecycle of an application or application component in the cloud environment.
The following image is the graphical representation of the 2025 Magic Quadrant for Cloud-Native Application Platforms.
Our comprehensive cloud-native application portfolio—AWS Lambda, AWS App Runner, AWS Amplify, and AWS Elastic Beanstalk—offers flexible options for building modern applications with strong AI capabilities, demonstrated through continued innovation and deep integration across our broader AWS service portfolio.
You can simplify the service selection through comprehensive documentation, reference architectures, and prescriptive guidance available in the AWS Solutions Library, along with AI-powered, contextual recommendations from Amazon Q based on your specific requirements. While AWS Lambda is optimized for AWS to provide the best possible serverless experience, it follows industry standards for serverless computing and supports common programming languages and frameworks. You can find all necessary capabilities within AWS, including advanced features for AI/ML, edge computing, and enterprise integration.
2025 Gartner Magic Quadrant for Container Management In the 2025 Gartner Magic Quadrant for Container Management, AWS has been named as a Leader for three years and was positioned furthest for “Completeness of Vision”. Gartner defines container management as offerings that support the deployment and operation of containerized workloads. This process involves orchestrating and overseeing the entire lifecycle of containers, covering deployment, scaling, and operations, to ensure their efficient and consistent performance across different environments.
The following image is the graphical representation of the 2025 Magic Quadrant for Container Management.
AWS container services offer fully managed container orchestration with AWS native solutions and open-source technologies to focus on providing a wide range of deployment options, from Kubernetes to our native orchestrator.
You can connect on-premises and edge infrastructure back to AWS container services with EKS Hybrid Nodes and ECS Anywhere, or use EKS Anywhere for a fully disconnected Kubernetes experience supported by AWS. With flexible compute and deployment options, you can reduce operational overhead and focus on innovation and drive business value faster.
Gartner does not endorse any vendor, product or service depicted in its research publications and does not advise technology users to select only those vendors with the highest ratings or other designation. Gartner research publications consist of the opinions of Gartner’s research organization and should not be construed as statements of fact. Gartner disclaims all warranties, expressed or implied, with respect to this research, including any warranties of merchantability or fitness for a particular purpose.
GARTNER is a registered trademark and service mark of Gartner and Magic Quadrant is a registered trademark of Gartner, Inc. and/or its affiliates in the U.S. and internationally and are used herein with permission. All rights reserved.
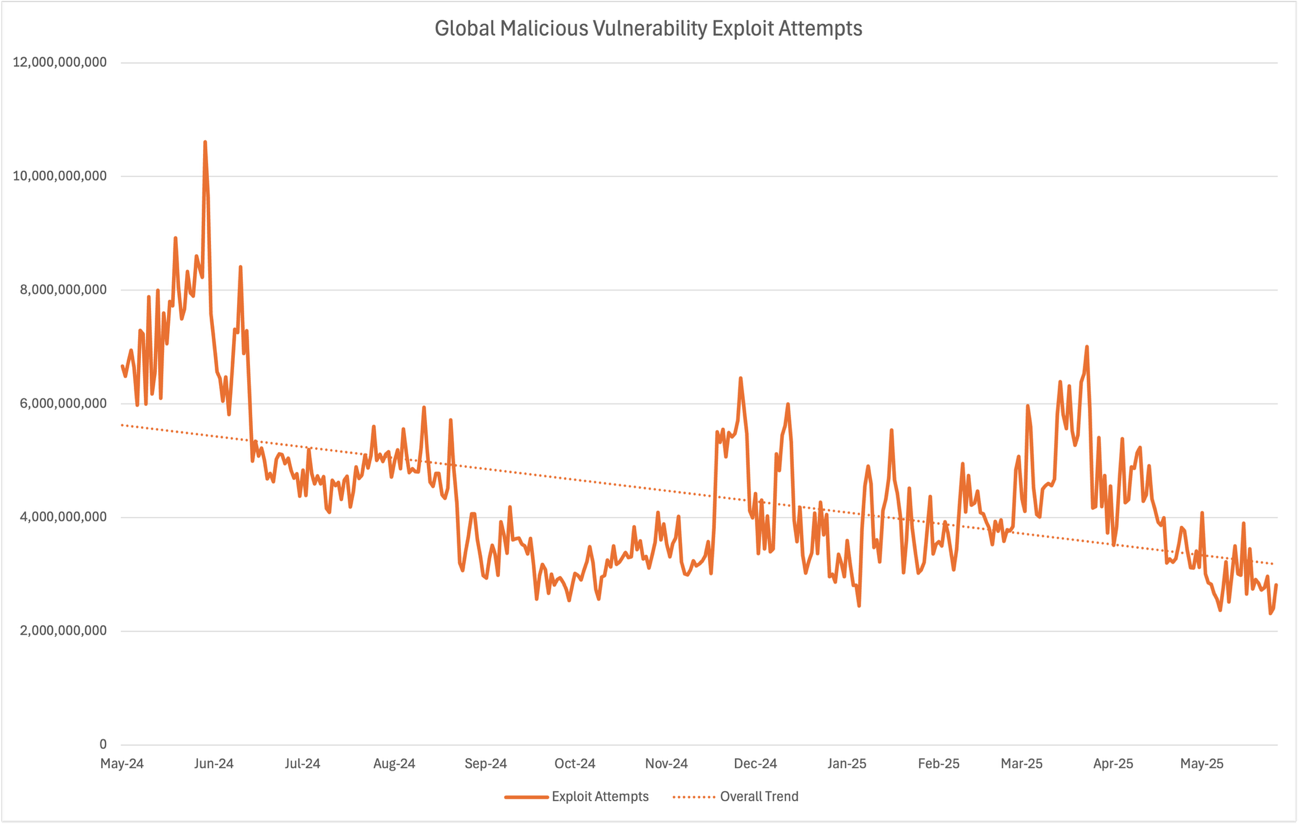
Amazon’s threat intelligence team has identified and disrupted a watering hole campaign conducted by APT29 (also known as Midnight Blizzard), a threat actor associated with Russia’s Foreign Intelligence Service (SVR). Our investigation uncovered an opportunistic watering hole campaign using compromised websites to redirect visitors to malicious infrastructure designed to trick users into authorizing attacker-controlled devices through Microsoft’s device code authentication flow. This opportunistic approach illustrates APT29’s continued evolution in scaling their operations to cast a wider net in their intelligence collection efforts.
The evolving tactics of APT29
This campaign follows a pattern of activity we’ve previously observed from APT29. In October 2024, Amazon disrupted APT29’s attempt to use domains impersonating AWS to phish users with Remote Desktop Protocol files pointed to actor-controlled resources. Also, in June 2025, Google’s Threat Intelligence Group reported on APT29’s phishing campaigns targeting academics and critics of Russia using application-specific passwords (ASPs). The current campaign shows their continued focus on credential harvesting and intelligence collection, with refinements to their technical approach, and demonstrates an evolution in APT29’s tradecraft through their ability to:
Compromise legitimate websites and initially inject obfuscated JavaScript
Rapidly adapt infrastructure when faced with disruption
On new infrastructure, adjust from use of JavaScript redirects to server-side redirects
Technical details
Amazon identified the activity through an analytic it created for APT29 infrastructure, which led to the discovery of the actor-controlled domain names. Through further investigation, Amazon identified the actor compromised various legitimate websites and injected JavaScript that redirected approximately 10% of visitors to these actor-controlled domains. These domains, including findcloudflare[.]com, mimicked Cloudflare verification pages to appear legitimate. The campaign’s ultimate target was Microsoft’s device code authentication flow. There was no compromise of AWS systems, nor was there a direct impact observed on AWS services or infrastructure.
Analysis of the code revealed evasion techniques, including:
Using randomization to only redirect a small percentage of visitors
Employing base64 encoding to hide malicious code
Setting cookies to prevent repeated redirects of the same visitor
Pivoting to new infrastructure when blocked
Image of compromised page, with domain name removed.
Amazon’s disruption efforts
Amazon remains committed to protecting the security of the internet by actively hunting for and disrupting sophisticated threat actors. We will continue working with industry partners and the security community to share intelligence and mitigate threats. Upon discovering this campaign, Amazon worked quickly to isolate affected EC2 instances, partner with Cloudflare and other providers to disrupt the actor’s domains, and share relevant information with Microsoft.
Despite the actor’s attempts to migrate to new infrastructure, including a move off AWS to another cloud provider, our team continued tracking and disrupting their operations. After our intervention, we observed the actor register additional domains such as cloudflare[.]redirectpartners[.]com, which again attempted to lure victims into Microsoft device code authentication workflows.
Protecting users and organizations
We recommend organizations implement the following protective measures:
For end users:
Be vigilant for suspicious redirect chains, particularly those masquerading as security verification pages.
Always verify the authenticity of device authorization requests before approving them.
Enable multi-factor authentication (MFA) on all accounts, similar to how AWS now requires MFA for root accounts.
Be wary of web pages asking you to copy and paste commands or perform actions in Windows Run dialog (Win+R).
This matches the recently documented “ClickFix” technique where attackers trick users into running malicious commands.
For IT administrators:
Follow Microsoft’s security guidance on device authentication flows and consider disabling this feature if not required.
Enforce conditional access policies that restrict authentication based on device compliance, location, and risk factors.
Implement robust logging and monitoring for authentication events, particularly those involving new device authorizations.
Indicators of compromise (IOCs)
findcloudflare[.]com
cloudflare[.]redirectpartners[.]com
Sample JavaScript code
Decoded JavaScript code, with compromised site removed: “[removed_domain]”
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
This post is co-written with Nazariy Popov, Volodymyr Konchuk, and Andrii Davydenko from EPAM
Legacy code modernization presents significant challenges for organizations looking to stay competitive in today’s rapidly evolving digital landscape. Organizations face the dual challenge of maintaining business continuity while modernizing their legacy systems for cloud environments. This transformation requires organizations to carefully navigate between preserving essential business logic and implementing modern architectural patterns. This is where AI-powered development tools can make a transformative impact, as demonstrated in EPAM’s recent legacy modernization project using Amazon Q Developer.
Amazon Q Developer, an AI code assistant, seamlessly integrates into the development pipeline to address these challenges. This innovative AI code assistant helps teams tackle various tasks, from generating new features, automating language upgrades, and refactoring legacy code to fixing bugs and automating deployments. By providing detailed explanations for its code suggestions while maintaining high quality standards, Amazon Q Developer significantly improves developer efficiency across the entire software development lifecycle, resulting in substantial time and effort savings.
EPAM, an AWS Premier Partner, collaborated with one of their customers to modernize their legacy applications to AWS Cloud. The modernization initiative focused on multiple business-critical applications, primarily built in Java 8 with Oracle Database backend.
In this post, you’ll learn how Amazon Q Developer helped EPAM engineers transform these complex legacy systems into modern cloud-native architectures on AWS. The tool enabled the team to autonomously perform a range of tasks—from implementing new microservices and documenting code to testing, reviewing, and refactoring Java code, as well as performing critical platform upgrades.
Before diving into the details, here’s an overview of how Amazon Q Developer helped EPAM across various aspects of the modernization project:
Summary of Amazon Q Developer Use Cases in EPAM’s Modernization Journey:
Let’s explore each of these areas in detail.
Enhancing developer efficiency (Estimated time savings: 60-70%)
Amazon Q Developer played a crucial role in boosting EPAM’s development productivity. By automating routine tasks and providing intelligent code suggestions, the tool enabled developers to focus on more strategic aspects of the modernization project. Let’s explore how EPAM leveraged these capabilities.
Use Case 1: Generating New API Endpoints
Creating new API endpoints traditionally requires developers to invest 1-2 days per endpoint, involving multiple steps from designing the API contract to writing unit tests and documentation. Using Amazon Q Developer, the team dramatically accelerated this process for three new API endpoints in an existing microservice. Q Developer efficiently generated the initial code implementation along with comprehensive unit test coverage, requiring only minor modifications such as renaming variables, enhancing error handling, and refining test cases. The unit tests generated proved remarkably reliable with minimal adjustments needed. Along with this, Q Developer also generated comprehensive comments/documentation of the code improving the maintainability. This reduced the total development time to just 4 hours for all three endpoints – a 70% time saving compared to the traditional approach, allowing developers to focus on fine-tuning business logic rather than writing boilerplate code.
Use Case 2: Integrating Legacy Systems
Integrating a legacy monolith application with modern microservices traditionally requires developers to manually write extensive integration code, taking 1-2 weeks per integration point. Amazon Q Developer accelerated this process by automatically generating REST API client code in the monolith to consume microservice endpoints, along with data transfer objects (DTOs), error handling, and retry logic with integration test templates. While developers still needed to validate business rules and fine-tune error scenarios, Q Developer’s ability to understand both the legacy monolith’s structure and modern microservice patterns reduced the integration time to 2-3 days per integration point – a 70% time saving. This significantly streamlined the integration process while maintaining the robustness required for production systems.
Use Case 3: Generating and Refactoring JPA Entity Classes
During the modernization effort, new database tables were required to support additional business functionality in both the monolith and microservices. Instead of manually coding the data access layer, Amazon Q Developer automated the process by generating Spring JPA Entity classes from SQL DDL statements. Amazon Q Developer maintained consistency with existing data models by following established naming conventions, applying standard annotations, and implementing required interfaces from the existing codebase. What stood out was Q Developer’s ability to provide detailed explanations for its implementation choices, such as why specific annotations were used or how the new entities aligned with existing persistence patterns, enabling the team to quickly validate the generated code against their architectural standards. Amazon Q Developer generated the complete Java Spring entity class with all the fields. Additionally, Amazon Q Developer refactored the Entity class as well.
Use Case 4: Streamlining Project Documentation
Creating and maintaining up-to-date project documentation is often a time-consuming task for developers. Amazon Q Developer simplified this process by assisting in the generation of README files for the team’s projects. By analyzing the project structure, dependencies, and key components, Q Developer produced initial drafts of README files that included project overviews, setup instructions, and API documentation. This allowed developers to quickly review and refine the documentation, ensuring it met team standards while saving significant time compared to writing everything from scratch.
Use Case 5: Enhancing Jira Ticket Descriptions
Writing detailed, informative Jira ticket descriptions can be a challenge, especially for complex features or bug fixes. Amazon Q Developer aided the team by suggesting detailed descriptions for Jira tickets based on the context of the code changes and related discussions. For example, when creating a ticket for a new feature, Q Developer could propose a description that included the feature’s purpose, key implementation details, and potential impact on other system components. While developers still needed to review and adjust these descriptions, the AI-generated starting point significantly reduced the time spent on ticket management, allowing the team to focus more on actual development work.
Transforming workloads (Estimated time savings: 65-75%)
Moving legacy applications to the cloud requires careful planning and execution. EPAM utilized Amazon Q Developer’s Java upgrade capabilities to streamline the transformation of monolithic applications into modern, cloud-native architectures. Here’s how the Amazon Q Developer facilitated this process.
Use Case 6: Modernizing and upgrading Java applications
Amazon Q Developer assisted in upgrading older Java applications to Java 21 to leverage modern features like Java Streams API and adapting it for Spring Boot tech stack. It not only upgraded the code, but also updated deprecated code components, dependencies and libraries as well. This modernization improved the code’s performance and also aligned it with the current best practices adopted by the development teams. For large monolithic applications, breaking/decomposing the monolith into logical groups while identifying and separating common modules as shared dependencies helped break down the problem into manageable pieces for the agent to do a better job, resulting in a more maintainable and modular structure for the transformation process. This modular approach significantly enhanced Q Developer’s ability to analyze and transform the codebase while reducing the complexity of the modernization effort.
Refactoring Code, Improving Code Quality and Readability (Estimated time savings: 60-75%)
One of the most challenging aspects of modernization is refactoring legacy code and maintaining high code quality standards. Amazon Q Developer assisted EPAM’s team in analyzing complex codebases and suggesting improvements, optimizing the code while preserving business logic and ensuring consistent code quality. The following examples demonstrate this capability in action.
Use Case 7: Refactoring Complex Methods
Legacy code often includes methods with high cyclomatic complexity, making them difficult to maintain. Amazon Q Developer helped the development team refactor large, complex methods into smaller, more readable, and better-structured methods. It also provided a detailed explanation of the changes, highlighting how the refactored code improved maintainability and readability.
Use Case 8: Renaming Across the Repository
When tasked with renaming ‘YTD Tax Report‘ to ‘Withholding Tax Report‘ across the entire repository, Amazon Q Developer demonstrated capabilities beyond simple search and replace functionality found in traditional IDEs. It performed context-aware renaming, distinguishing between instances where ‘YTD Tax Report‘ was part of larger phrases or variable names, while simultaneously updating related components including unit tests, integration tests, and logging statements. The tool intelligently refactored method signatures where the report name was part of method names or parameters, analyzed and updated database queries, and maintained consistency across different file types including Java, XML, and properties files. What set Q Developer apart was its ability to provide detailed change logs explaining each modification and the rationale behind more complex refactoring decisions, significantly reducing the risk of missed references or inconsistencies that often occur with manual search-and-replace operations.
Use Case 9: Code Review and fixes
The code review capabilities of Amazon Q Developer, seamlessly integrated into the IDE, enabled the development team to detect potential issues spanning multiple classes. Beyond merely identifying problems, Q Developer provided actionable fix recommendations that could be easily reviewed and implemented. This proactive approach to code quality allowed the team to address issues during the early stages of development, significantly reducing the likelihood of defects making their way to production environments.
Diagnosing and troubleshooting errors (Estimated time savings: 40-60%)
Quick error resolution is crucial for maintaining development momentum. Amazon Q Developer’s advanced error analysis capabilities helped EPAM’s team identify and fix issues efficiently, reducing debugging time significantly. Here are some examples of how this worked in practice.
Use Case 10: Root Cause Analysis and Fix
During the development phase, the team encountered an unexpected error in one of the Java services: java.lang.IllegalArgumentException: Property 'http://javax.xml.XMLConstants/property/accessExternalDTD' is not recognized. Q Developer conducted a deeper analysis based on the context provided and suggested a more targeted fix and generated the necessary Java code changes, provided unit tests to verify the fix, and outlined potential security implications of the change. This comprehensive solution not only resolved the immediate error but also improved the overall security posture of the XML processing in the application. The team was able to implement and verify the fix within minutes, significantly reducing development.
Use Case 11: Fixing Database Connection Issues
While troubleshooting an issue where the application became unresponsive due to JDBC connection problems, Amazon Q Developer analyzed the project code and identified the missing connection pool configuration. Q Developer suggested implementing essential connection pool parameters like 'maximumPoolSize=20' and 'connectionTimeout=30000' based on the application’s traffic patterns and code. After implementing its suggested configuration, the issue was resolved, significantly improving the application’s stability.
Use Case 12: Complex SQL Query Analysis
Debugging complex SQL queries constructed dynamically in Java code can be challenging. Amazon Q Developer analyzed such queries, broke them down into their component parts, and provided descriptions for query parameters. For instance, when presented with a complex query involving multiple joins and subqueries, Q Developer dissected it into logical blocks, explaining how each part contributed to the overall result set. This made it easier for the team to understand and debug the queries.
Testing and Deployment: Test data generation and Automating Infrastructure Setup (Estimated time savings: 30-50%)
Use Case 13: Generating JSON Request Bodies
When testing new APIs, Amazon Q Developer generated JSON request bodies based on the corresponding Java classes. It provided detailed descriptions of each field and suggested realistic and meaningful default values, making it easier to validate API functionality with real-world scenarios.
Use Case 14: Generating SQL Test Data
Amazon Q Developer generated SQL insert statements with test data based on our existing Java Entity classes. This automation saved us a significant amount of time in creating realistic test data for database validation and integration testing.
Use Case 15: Generating Deployment Files
Amazon Q Developer helped the development team generate essential deployment artifacts, including a Docker file, a startup shell script that was used as an entry point, and a Kubernetes deployment file for a new service. Automating this process not only saves time but also improves consistency across environments.
Ready to transform your developer experience?
EPAM’s experience with Amazon Q Developer has been transformative, significantly accelerating their application modernization efforts while maintaining high code quality. By leveraging Amazon Q Developer, EPAM reduced development time by approximately 70% and improved code quality metrics across the client’s portfolio. This efficiency gains not only accelerated the client’s cloud migration timeline but also resulted in substantial cost savings and faster time-to-market for new features.
Now, it’s your turn to explore Amazon Q Developer:
Schedule a demo: Experience firsthand how Amazon Q Developer can accelerate your development lifecycle. Connect with our team for a personalized demonstration tailored to your specific use case.
Start Your Proof of Concept: Begin your journey with Amazon Q Developer today through a proof of concept. See how it can enhance your team’s productivity and code quality, just as it did for EPAM.
Connect with EPAM: Learn more about EPAM’s success story and best practices for implementing Amazon Q Developer in your organization’s development workflow.
Take the next step in revolutionizing your development process. Visit Amazon Q Developer website or contact your AWS account team to get started.
Authors
EPAM
Nazariy Popov, Delivery Head of GenAI Engineering and Modernization Practice Delivery management professional and technology leader with over 15 years of experience in the IT industry. At EPAM, he drives large-scale transformation programs, focusing on enterprise software development, cloud solutions, and AI assisted engineering and modernization.
Volodymyr Konchuk, Lead Software Engineer Java engineer with more than 11 years of production experience in Java-based web and enterprise applications. Has experience in building ecommerce and retail business applications using Java, Spring tech stack, and Amazon Web Services.
Andrii Davydenko, Delivery Manager Seasoned delivery lead with over 7 years of experience managing ecommerce modernization projects with a focus on application performance optimization.
AWS
Venugopalan Vasudevan (Venu) is a Senior Specialist Solutions Architect focusing on Next Generation Developer Experience and AWS Generative AI services. In this role, Venu, helps organizations optimize their development processes and accelerate their digital transformation journeys using Amazon Q Developer and other AWS Generative AI Services. Also, Venu partners with enterprises to architect and implement Generative AI solutions while establishing robust development practices.
Arun Chandapillai is a Senior Engineering Architect with a strong history of leading cross-functional teams and collaborating with executive stakeholders. He is passionate about helping customers accelerate IT modernization through business-first cloud adoption strategies, with a focus on leveraging generative AI and MLOps. Outside of technology, he is an automotive enthusiast who loves the thrill of the open road, an engaging public speaker, and a philanthropist who lives by the motto ‘you get (back) what you give’.
Jasmine Rasheed Syed is a Senior Customer Solutions manager, focused in accelerating time to value for the customers in their in cloud journey by adopting best practices and mechanisms to transform their business at scale. Jasmine is a seasoned, result oriented leader with 20+ years of progressive experience in Insurance, Retail & CPG with exemplary track record spanning across Business Development, Cloud/Digital Transformation, Delivery, Operational & Process Excellence and Executive Management.
Oscar Hernandez is a Senior Account Executive, helping global organizations drive digital and AI transformation at scale. He works closely with executive teams to integrate cloud and AI-driven solutions that address complex business challenges and deliver measurable enterprise-wide impact. With over 15 years of experience across IT, telecom, financial services, retail, and HR technology, he focuses on enabling innovation, optimizing operations, and maximizing the value of emerging technologies.
On August 4, 2025, Gartner published its Gartner Magic Quadrant for Strategic Cloud Platform Services (SCPS). Amazon Web Services (AWS) is the longest-running Magic Quadrant Leader, with Gartner naming AWS a Leader for the fifteenth consecutive year.
In the report, Gartner once again placed AWS highest on the “Ability to Execute” axis. We believe this reflects our ongoing commitment to giving customers the broadest and deepest set of capabilities to accelerate innovation as well as unparalleled security, reliability, and performance they can trust for their most critical applications.
Here is the graphical representation of the 2025 Magic Quadrant for Strategic Cloud Platform Services.
Gartner recognized AWS strengths as:
Largest cloud community – AWS has built a strong global community of cloud professionals, providing significant opportunities for learning and engagement.
Cloud-inspired silicon – AWS has used its cloud computing experience to develop custom silicon designs, including AWS Graviton, AWS Inferentia, and AWS Trainium, which enable tighter integration between hardware and software, improved power efficiency, and greater control over supply chains.
Global scale and operational execution – AWS’s significant share of global cloud market revenue has enabled it to build a larger and more robust network of integration partners than some other providers in this analysis, which in turn helps organizations successfully adopt cloud.
The most common feedback I hear from customers is that AWS has the largest and most dynamic cloud community, making it easy to ask questions and learn from millions of active customers and tens of thousands of partners globally. We recently launched our community hub, AWS Builder Center to connect directly with AWS Heroes and AWS Community Builders. You can also explore and join AWS User Groups and AWS Cloud Clubs in a city near you.
We have also focused on facilitating the digital transformation of enterprise customers through a number of enterprise programs, such as the AWS Migration Acceleration Program. Using generative AI on migration and modernization, we introduced AWS Transform, the first agentic AI service developed to accelerate enterprise modernization of mission-critical business workloads such as .NET, mainframe, and VMware.
Access the complete full Gartner report to learn more. It outlines the methodology and evaluation criteria used to develop their assessments of each cloud service provider included in the report. This report can serve as a guide when choosing a cloud provider that helps you innovate on behalf of your customers.
Gartner does not endorse any vendor, product or service depicted in its research publications and does not advise technology users to select only those vendors with the highest ratings or other designation. Gartner research publications consist of the opinions of Gartner’s research organization and should not be construed as statements of fact. Gartner disclaims all warranties, expressed or implied, with respect to this research, including any warranties of merchantability or fitness for a particular purpose.
GARTNER is a registered trademark and service mark of Gartner and Magic Quadrant is a registered trademark of Gartner, Inc. and/or its affiliates in the U.S. and internationally and are used herein with permission. All rights reserved.
Ten years ago, we announced the general availability of Amazon Aurora, a database that combined the speed and availability of high-end commercial databases with the simplicity and cost-effectiveness of open source databases.
As Jeff described it in its launch blog post: “With storage replicated both within and across three Availability Zones, along with an update model driven by quorum writes, Amazon Aurora is designed to deliver high performance and 99.99% availability while easily and efficiently scaling to up to 64 TiB of storage.”
When we started developing Aurora over a decade ago, we made a fundamental architectural decision that would change the database landscape forever: we decoupled storage from compute. This novel approach enabled Aurora to deliver the performance and availability of commercial databases at one-tenth the cost.
This is one of the reasons why hundreds of thousands of AWS customers choose Aurora as their relational database.
A brief look back at the past Throughout the evolution of Aurora, we’ve focused on four core innovation themes: security as our top priority, scalability to meet growing workloads, predictable pricing for better cost management, and multi-Region capabilities for global applications. Let me walk you through some key milestones in the Aurora journey.
The journey continued with the serverless preview in November 2017, which became generally available in August 2018. Global Database launched in November 2018 for cross-Region disaster recovery. We introduced blue/green deployments to simplify database updates, and optimized read instances to improve query performance.
In 2023, we added vector capabilities with pgvector for similarity search for Aurora PostgreSQL, and Aurora I/O-Optimized to provide predictable pricing with up to 40 percent cost savings for I/O-intensive applications. We launched Aurora zero-ETL integration with Amazon Redshift which enables near real-time analytics and ML using Amazon Redshift on petabytes of transactional data from Aurora by removing the need for you to build and maintain complex data pipelines that perform extract, transform, and load (ETL) operations. This year we added Aurora MySQL zero-ETL integration with Amazon Sagemaker, enabling near real-time access of your data in the lakehouse architecture of SageMaker to run a broad range of analytics.
To simplify scaling for customers, we also increased the maximum storage to 128 TiB in September 2020, allowing many applications to operate within a single instance. Last month, we’ve further simplified scaling by doubling the maximum storage to 256 TiB, with no upfront provisioning required and pay-as-you-go pricing based on actual storage used. This enables even more customers to run their growing workloads without the complexity of managing multiple instances while maintaining cost efficiency.
Most recently, at re:Invent 2024, we announced Amazon Aurora DSQL, which became generally available in May 2025. Aurora DSQL represents our latest innovation in distributed SQL databases, offering active-active high availability and multi-Region strong consistency. It’s the fastest serverless distributed SQL database for always available applications, effortlessly scaling to meet any workload demand with zero infrastructure management.
Aurora DSQL builds on our original architectural principles of separation of storage and compute, taking them further with independent scaling of reads, writes, compute, and storage. It provides 99.99% single-Region and 99.999% multi-Region availability, with strong consistency across all Regional endpoints.
Let’s celebrate 10 years of innovation By attending the August 21 livestream event, you’ll hear from Aurora technical leaders and founders, including Swami Sivasubramanian, Ganapathy (G2) Krishnamoorthy, Yan Leshinsky, Grant McAlister, and Raman Mittal. You’ll learn directly from the architects who pioneered the separation of compute and storage in cloud databases, with technical insights into Aurora architecture and scaling capabilities. You’ll also get a glimpse into the future of database technology as Aurora engineers share their vision and discuss the complex challenges they’re working to solve on behalf of customers.
The event also offers practical demonstrations that show you how to implement key features. You’ll see how to build AI-powered applications using pgvector, understand cost optimization with the new Aurora DSQL pricing model, and learn how to achieve multi-Region strong consistency for global applications.
The interactive format includes Q&A opportunities with Aurora experts, so you’ll be able to get your specific technical questions answered. You can also receive AWS credits to test new Aurora capabilities.
If you’re interested in agentic AI, you’ll particularly benefit from the sessions on MCP servers, Strands Agents, and how to integrate Strands Agents with Aurora DSQL, which demonstrate how to safely integrate AI capabilities with your Aurora databases while maintaining control over database access.
Whether you’re running mission-critical workloads or building new applications, these sessions will help you understand how to use the latest Aurora features.
Register today to secure your spot and be part of this celebration of database innovation.
The guest data of AWS customers running on the AWS Nitro System and Nitro Hypervisor is not at risk from a new attack dubbed “L1TF Reloaded.” No additional action is required by AWS customers; however, AWS continues to recommend that customers isolate their workloads using instance, enclave, or function boundaries as described in AWS public documentation. The AWS Nitro System and Nitro Hypervisor are designed to help protect against this class of attacks.
The Nitro Hypervisor’s protection against L1TF Reloaded is not the result of a specific patch or reactive mitigation, but rather due to the proactive approach to security at AWS. The fundamental security design principles of the Nitro Hypervisor—particularly the implementation of secret hiding through an extensive use of the eXclusive Page Frame Ownership (XFPO) concept (in some contexts referred to as process-localmemory)—provides robust protection against this class of attacks. L1TF Reloaded represents an innovative approach to transient execution attacks, showing how threat actors can combine seemingly mitigated vulnerabilities to create new attacks that are more than the sum of their parts. The research is impressive and constructs a multilayer end-to-end exploit with real-world applicability. AWS sponsored a portion of this work and would like to thank the researchers for their collaboration and coordinated disclosure. The remainder of this post is a deeper dive into the published research.
The Nitro Hypervisor: Purpose-built for security
The Nitro Hypervisor is a foundational component of the AWS Nitro System, designed from the ground up with security as a primary consideration. Unlike traditional hypervisors that evolved from general-purpose operating systems, the Nitro Hypervisor, which is based on Linux/Kernel-based Virtual Machine (KVM), has been intentionally minimized and purpose-built with only the capabilities needed to perform its assigned functions.
The Nitro Hypervisor’s responsibilities are deliberately constrained: it receives virtual machine (VM) management requests from the Nitro Controller, partitions memory and CPU resources using hardware virtualization features, and assigns PCIe devices, including both Physical (PF) and Single Root I/O Virtualization (SR-IOV) Virtual Functions (VF) provided by Nitro hardware (such as NVMe for EBS and instance storage, and Elastic Network Adapter for networking) and third party devices (GPUs), to VMs. Critically, the Nitro Hypervisor excludes entire categories of functionality that exist in conventional hypervisors. There is no networking stack, no general-purpose file system implementations, no peripheral device-driver support, no shell, and no interactive access mode. This meticulous exclusion of non-essential features helps avoid entire classes of issues and attack vectors that can impact other hypervisors, such as remote networking attacks or driver-based privilege escalations.
Understanding transient execution vulnerabilities
To understand why the Nitro Hypervisor’s defenses are effective against L1TF Reloaded, it is important to first understand the fundamentals of transient execution vulnerabilities that emerged in 2018. Modern CPUs implement out-of-order and prediction-based speculative execution to optimize performance by executing operations before they are needed or before the CPU knows whether it should perform them at all. When predictions are wrong, or the CPU encounters execution faults, the CPU will eventually detect these errors and roll back all speculatively computed changes to the architectural state. However, traces of these “transient executions” remain detectable in the microarchitectural state, such as data that was speculatively loaded into CPU caches, creating opportunities for data leakage through side-channel attacks.
Half-Spectre gadgets: Incomplete but dangerous code patterns
While traditional Spectre attacks require complete “gadgets” that both access secret data and transmit it through side channels, researchers have identified a weaker class of gadgets called “half-Spectre gadgets.” These are incomplete Spectre-like code patterns that perform speculative out-of-bounds memory accesses, but lack the transmission component that would make them immediately exploitable.
A classic Spectre v1 gadget contains two key elements: first, a speculative access that loads secret data (such as x = A[index] where index is out of bounds), and second, a transmission mechanism that leaks the data through a side channel (such as y = B[64 * x] that creates cache patterns based on the secret value). Half-Spectre gadgets contain only the first element—the speculative access—without the transmission component.
Because half-Spectre gadgets appear harmless in isolation, they are commonly found throughout software, including hypervisors. These gadgets typically arise from array-indexing operations where bounds checking occurs, but the transient execution window allows out-of-bounds access before the bounds check resolves. The gadgets can be either absolute (directly providing the address to access) or relative (controlling an offset from a base address), with relative gadgets being more common due to typical array indexing patterns. The key insight of L1TF Reloaded is that half-Spectre gadgets, while harmless alone, become dangerous when combined with other vulnerabilities like L1TF. A threat actor can trigger a half-Spectre gadget in the hypervisor to speculatively load arbitrary data into the L1 data cache and then use L1TF to extract that cached data—effectively turning the “harmless” half-Spectre gadget into a complete gadget.
L1 Terminal Fault (L1TF), discovered in January 2018 and disclosed in August 2018, represents a significant type of transient execution vulnerability that affects Intel processors up to Coffee Lake. These processors are used in some 5th generation EC2 instance families and all older instance types. L1TF leverages faulty address translations during transient execution when accessing invalid page table entries. Under normal operation, when a CPU encounters a Page Table Entry (PTE) with the present bit cleared or reserved bits set, address translation should halt immediately. However, during transient execution, Intel processors affected by L1TF ignore these invalid page table states and utilize a partially translated address. If the target data exists in the L1 data cache, the CPU will speculatively load it and make it available to subsequent instructions, even though the access should be blocked. This behavior is particularly problematic in virtualized environments. A malicious guest operating system can deliberately clear present bits in its own page tables to trigger terminal faults. When this happens, the CPU skips the normal host address translation process and passes the guest physical address directly to the L1 data cache. This allows the threat actor to potentially read any cached physical memory on the system, regardless of ownership or privilege boundaries. For affected processors, comprehensive software mitigation requires expensive measures, like disabling Simultaneous Multi-Threading (SMT), flushing the L1 data cache on every context switch, or disabling Extended Page Tables (EPT) entirely—performance costs so significant that many systems implement only partial mitigations.
The L1TF Reloaded attack: Exploiting mitigation gaps using Spectre
The research paper demonstrates how threat actors can combine half-Spectre gadgets with L1TF to create a powerful attack vector against hypervisors that lack complete implementation of the previously outlined mitigations. The attack shows that vulnerabilities considered individually mitigated can still be leveraged if combined in novel ways. L1TF Reloaded works by leveraging the fact that while L1TF mitigations like L1 data cache flushing and core scheduling help prevent guest-to-guest attacks, they do not fully mitigate guest-to-host attacks. The attack operates across logical cores that share the L1 data cache in an SMT core. On one logical core, the threat actor triggers a half-Spectre gadget. By mistraining the branch predictor, the threat actor causes the hypervisor to speculatively access out-of-bounds memory, loading sensitive data into the shared L1 data cache. Simultaneously, on the other logical core, the threat actor uses L1TF to extract the cached data. While other research papers have demonstrated L1TF exploitation, this research paper has successfully demonstrated a multilayer end-to-end attack on upstream Linux/KVM and other cloud providers. The authors were able to use an existing half-Spectre gadget, break host Kernel Address Space Layout Randomization (KASLR), gain host address translation capability, find all the processes running on the host, identify the victim VM, break guest KASLR, gain guest address translation capability, identify the init process in the victim VM, enumerate the child processes of the init process, identify the nginx webserver process, locate the private TLS certificate in the guest process heap, and finally leak the private TLS certificate. However, when they attempted the same attack on AWS instances, they encountered a critical limitation: while they could leak some non-sensitive host data, they were unable to access guest data due to what they described as “an undocumented defense in the hypervisor that unmaps victim data from it. This “undocumented defense” is the Nitro Hypervisor’s implementation of secret hiding—a fundamental architectural decision that prevented this type of attack.
Traditional hypervisor designs follow a hierarchical privilege model where each higher level of privilege is granted access to all lower level memory. In conventional systems, the hypervisor running at the highest privilege level can access all VM memory, ostensibly for legitimate management purposes. However, this design creates a vulnerability: if a threat actor can trick the hypervisor into speculatively accessing guest data, that data becomes available for extraction through side-channel attacks. The Nitro Hypervisor takes a fundamentally different approach through a technique called secret hiding. Instead of following the traditional model where the hypervisor has access to all VM memory (Figure 1), the Nitro Hypervisor makes sure that guest data is not present in the hypervisor’s virtual address space. By removing VM memory pages from the hypervisor’s virtual address space (Figure 2), we avoid the possibility of transient execution attacks accessing guest data, even if a threat actor successfully triggers gadgets within the hypervisor.
Figure 1: Memory view of the hypervisor without mitigations in the context of VM1
Figure 2: Memory view of the Nitro Hypervisor in the context of VM1. While no guest memory is mapped, only the state of the active guest can be accessed with other guest states remaining inaccessible.
This architectural decision means that when transient execution occurs in the Nitro Hypervisor—whether through L1TF, half-Spectre gadgets, or other transient execution vulnerabilities—there is simply no guest data available to be leaked, creating a barrier against this class of vulnerabilities. The Nitro Hypervisor retains access only to its own data, but guest data remain isolated and inaccessible. While we could not anticipate L1TF Reloaded exactly, we knew transient execution vulnerabilities would continue to be discovered and built defense-in-depth mechanisms which blocked extraction of guest data on AWS instances. This design decision was made proactively during the Nitro Hypervisor development, based on our threat model that explicitly includes guest-to-host attacks that exploit the hypervisor. By assuming that threat actors might find ways to trigger transient execution vulnerabilities within the Nitro Hypervisor—whether through known vulnerabilities like L1TF or future unknown attack vectors—we designed the system to limit the scope of such attacks from the outset.
Beyond memory: Protecting guest CPU context
When VMs are scheduled and context-switched, guest CPU context information such as general-purpose and floating-point register content must be saved and restored. Guest CPU context can contain highly sensitive information. Registers might contain cryptographic keys, memory addresses that could defeat Address Space Layout Randomization (ASLR), or other secrets that applications rely on for security. In traditional hypervisors, guest CPU context is often stored in memory accessible to the hypervisor, creating another potential target for transient execution attacks. The original XPFO (eXclusive Page Frame Ownership) implementation makes sure that either user space or the kernel—but not both—can access a memory page and does not protect guest CPU context since it is exclusively owned by the kernel. The Nitro Hypervisor extends the XPFO concept to guest CPU context by saving it in memory—also known as process-local memory—that is solely mapped by process-specific kernel Page Table Entries (PTEs), as is shown in Figure 2 above. This memory is specifically designed to be only accessible from the Nitro Hypervisor in the context of the process it belongs to. This makes sure that even if a threat actor successfully triggers transient execution vulnerabilities within the Nitro Hypervisor, they cannot access the guest CPU context from other guests. The researchers confirmed this protection, noting that the AWS threat model accounts for guest-to-host attacks and that secret hiding, combined with existing L1 data cache flushing and core scheduling, prevented them from leaking guest data. This comprehensive approach to secret hiding demonstrates the defense-in-depth philosophy of the Nitro System: rather than protecting only known attack vectors, AWS systematically identifies and protects potential sources of guest data leakage, including both VM memory and guest CPU context.
Applying secret hiding principles to Xen
Most AWS Xen instances are now running on the AWS Nitro System and hence enjoy the benefits of the Nitro Hypervisor thanks to Xen-on-Nitro. For our portfolio of instance families running on the AWS Xen Hypervisor, we have implemented similar secrethiding principles to provide protection against transient execution attacks.
Defense in depth: The Nitro Hypervisor’s proven security model
L1TF Reloaded represents an important advancement in our understanding of how seemingly mitigated vulnerabilities can be combined to create new attack vectors. The researchers of the Rain paper demonstrated how L1TF and half-Spectre gadgets can work together to leak guest data from hypervisors. We are pleased to support their work and collaborate with them. The Nitro Hypervisor’s protection against L1TF Reloaded is not the result of a specific patch or reactive mitigation, but rather due to AWS deeply investing in securing multi-tenant cloud environments against sophisticated adversaries. This research reinforces our confidence in the Nitro System’s security model against both known and unknown attack vectors. The proactive security approach of AWS includes designing systems with defense-in-depth principles from the ground up. The threat landscape will continue to evolve, and at the same time, the defense-in-depth mechanisms built into the Nitro Hypervisor and our other products and services will continue to help protect AWS customers from sophisticated attacks, while maintaining the performance and functionality they depend on.
At Amazon Web Services (AWS), customer privacy and security are our top priority. We provide our customers with industry-leading privacy and security when they use the AWS Cloud anywhere in the world. In recent months, we’ve noticed an increase in inquiries about how we manage government requests for data. While many of the questions center around a 2018 U.S. law known as the Clarifying Lawful Overseas Use of Data Act (CLOUD Act), the CLOUD Act in fact did not give the U.S. government any new authority to compel data from providers and provides critical legal guardrails to protect content.
To put this whole issue in context—there have been no data requests to AWS that resulted in disclosure to the U.S. government of enterprise or government content data stored outside the U.S. since we started reporting the statistic in 2020. Our commitment to protecting customer data is underpinned by several layers of legal, technical, and operational protection. For example, AWS has designed its core products and services to prevent anyone but the customer and those authorized by the customer from accessing the customer’s content. And in these instances, any government that wants access to the customer’s content would have to seek that data directly from the customer. Additionally, U.S. law itself provides numerous statutory protections that help lower the risk that AWS could be required to disclose enterprise or government content data, and the U.S. Department of Justice (DOJ) has implemented additional operational protections over the past eight years.
With that in mind, we want to address some common misconceptions about the CLOUD Act and provide some clarity about how this law impacts—or doesn’t impact—AWS customers worldwide. We’re also expanding our FAQs on the CLOUD Act to help our customers and partners better navigate this topic.
Fact 1: The CLOUD Act does not give the U.S. government unfettered or automatic access to data stored in the cloud
The CLOUD Act was passed to address challenges law enforcement faced in obtaining data stored abroad in cross-border investigations involving serious crimes, ranging from terrorism and violent crime to sexual exploitation of children and cybercrime. The CLOUD Act primarily enabled the U.S. to enter into reciprocal executive agreements with trusted foreign partners to obtain access to electronic evidence for investigations of serious crimes, wherever the evidence happens to be located, by lifting blocking statutes under U.S. law. Many governments rely on domestic laws to require providers within their jurisdiction to disclose electronic data under the companies’ control, regardless of where the data is stored. Similarly, The CLOUD Act clarified that U.S. law enforcement can use existing authorities such as a court-approved search warrant to compel data within a provider’s control, regardless of where the data is stored; the executive agreements enable the effectiveness of these reciprocal laws, supported by strong procedural and substantive safeguards.
Access to data under U.S. law is far from unfettered or automatic, and law enforcement must meet strict legal standards. Under U.S. law, providers are actually prohibited from disclosing data to the U.S. government absent a legal exception. To compel a provider to disclose content data, law enforcement must convince an independent federal judge that probable cause exists related to a particular crime, and that evidence of the crime will be found in the place to be searched (that is, a specific electronic account such as an email account). This legal standard must be established through specific and trustworthy facts. Each search warrant must pass this stringent probable cause determination using credible facts, particularity, and legality, must receive approval from an independent judge, and must meet requirements regarding scope and jurisdiction. In May 2023, the DOJ also issued a policy that prosecutors seeking evidence known to be located abroad must obtain approval from Department’s Office of International Affairs (OIA) prior to obtaining an order for such evidence. The DOJ policy on evidence abroad notes that every nation enacts laws to protect its sovereignty; OIA works to address these issues and assist prosecutors in selecting an appropriate mechanism to secure evidence.
Fact 2: AWS has not disclosed any enterprise or government customer content data under the CLOUD Act since we started tracking the statistic
AWS has rigorous procedures in place for handling law enforcement requests from any country to validate legitimacy and verify that they comply with applicable law. AWS recognizes the legitimate needs of law enforcement agencies in investigating criminal and terrorist activity, but they must observe legal safeguards for conducting such investigations. We do not disclose customer data in response to any government request unless we are obligated to do so by a legally valid and binding order. We have publicly committed to this in our legal terms. Additionally, we will challenge government requests that conflict with the law, are overbroad, or are otherwise inappropriate (for example, if such a request would violate individuals’ fundamental rights). When we receive such requests for enterprise customer content, we make every reasonable effort to redirect law enforcement to the customer and notify the customer when legally permitted. If we are required to disclose customer content, we notify customers before disclosure to provide them an opportunity to seek protection from disclosure unless prohibited by law. If after exhausting these steps, AWS remains compelled to disclose customer data, and we have the technical ability to do so (which, as described above, in many instances we do not), we disclose only the minimum necessary to satisfy the legal process.
Consistent with our policy to redirect law enforcement to customers, the DOJ’s Computer Crime and Intellectual Property Section has also issued guidance advising prosecutors to generally seek data directly from an enterprise, such as a company that stores data with a cloud provider, rather than from the provider.
A clear measure of the effectiveness of our measures and the rigorous legal requirements embodied in law is the fact that since we began reporting this statistic in 2020, AWS has not disclosed any enterprise or government customer content data stored outside the U.S. to the U.S. government. This record reflects the technical safeguards AWS offers, the robust legal protections within U.S. law, policies implemented by the DOJ, and the nature of law enforcement investigations which primarily focus on collecting electronic evidence from consumer accounts.
Fact 3: The CLOUD Act does not only apply to U.S.-headquartered companies—it applies to all providers that do business in the United States
The CLOUD Act applies to all electronic communication service or remote computing service providers that operate or have a legal presence in the U.S.—regardless of where their headquarters are located. For example, European-headquartered cloud providers with U.S. operations are also subject to the Act’s requirements. OVHcloud, a French headquartered cloud service provider that operates in the U.S., notes in its CLOUD Act FAQ page that “OVHcloud will comply with lawful requests from public authorities. Under the CLOUD Act, that could include data stored outside of the United States.” Similarly, other cloud providers headquartered in the E.U. and elsewhere, also have operations in the U.S.
Fact 4: The principles in the CLOUD Act are consistent with international law and the laws of other countries
The CLOUD Act did not introduce a new legal concept regarding the scope of electronic data that must be disclosed as part of legitimate criminal investigations. Many countries require disclosure of customer data wherever it’s stored in response to legal process involving serious crimes. The United Kingdom’s (U.K.’s) Crime (Overseas Production Orders) Act, for instance, allows U.K. law enforcement agencies to obtain stored electronic data located outside of the U.K. in connection to a criminal investigation. According to a 2024 filing by the U.S. DOJ, the laws of several European Union member states, including Belgium, Denmark, France, Ireland, and Spain, have similar requirements. In fact, since 2023, most law enforcement requests that AWS receives come from authorities outside of the United States.
This concept is also enshrined within the Budapest Convention on Cybercrime, which was the first international treaty aimed at improving cooperation in investigations of cybercrimes. Additionally, the EU’s e-Evidence Regulation, 2023/1543, adopted in August 2023, authorizes Member States to “order a service provider…to produce or preserve electronic evidence regardless of the location of data.” The GDPR also allows for transfers of personal data in response to compelled disclosure requests from third countries, provided that the relevant party can cite an appropriate legal basis and transfer mechanism or derogation (see EDPB’s recent Guidelines 02/2024 on Article 48).
AWS is advocating for governments to conclude reciprocal executive agreements under the CLOUD Act, including between the U.S. and the European Union, and the U.S. and Canada. We believe these agreements are important to definitively resolve potential conflicts of law and enable effective investigation of serious crimes to advance public safety, while recognizing the strong substantive and procedural safeguards that already exist under U.S. law.
Fact 5: The CLOUD Act does not limit the technical measures and operational controls AWS offers to customers to prevent unauthorized access to customer data
We can only respond to legal requests for data where we have the technical ability to do so. AWS has a number of products and services designed to make sure that no one—not even AWS operators—can access customer content. AWS customers also have a range of additional technical measures and operational controls to prevent access to data. For example, many of the AWS core systems and services are designed with zero operator access, meaning the services don’t have any technical means for AWS operators to access customer data in response to a legal request.
The AWS Nitro System, which is the foundation of AWS computing services, uses specialized hardware and software to protect data from outside access during processing on Amazon Elastic Compute Cloud (Amazon EC2). By providing a strong physical and logical security boundary, Nitro is designed so that no unauthorized person—not even AWS operators—can access customer workloads on EC2. The design of the Nitro System has been validated by the NCC Group, an independent cybersecurity firm. The controls that help prevent operator access are so fundamental to the Nitro System that we’ve added them in our AWS Service Terms to provide an additional contractual assurance to all of our customers.
We also give customers features and controls to encrypt data, whether in transit, at rest, or in memory. All AWS services already support encryption, with most also supporting encryption with customer managed keys that are inaccessible to AWS. AWS Key Management Service (AWS KMS) is the first highly scalable, cloud-native key management system with FIPS 140-3 Security Level 3 certification. In plain English, this means AWS offers encryption that is super strong and where our customers control who gets a key.
Continuing our customer obsession
At AWS, our customer-first approach drives everything we do—from how we design our services to how we protect your data. We understand that your trust is earned through transparency, strong technical controls, and unwavering advocacy for your interests. That’s why we’ve been clear about how we handle government requests for data, including the impact of the CLOUD Act, and the multiple layers of protection—legal, operational, and technical—to safeguard your data.
We encourage you to learn more about this important topic by reviewing our expanded CLOUD Act FAQ. We will continue to innovate on your behalf, building new features and services that put you in control of your data, and maintaining our commitment to the highest standards of privacy and security.
French version
CLOUD Act : cinq points clés pour comprendre son fonctionnement réel
Chez Amazon Web Services (AWS), la confidentialité et la sécurité des clients constituent notre priorité absolue. Nous mettons à leur disposition une confidentialité et une sécurité à la pointe de l’industrie lorsqu’ils utilisent le Cloud AWS, partout dans le monde. Ces derniers mois, nous avons constaté une augmentation des questions concernant notre gestion des demandes d’accès aux données émanant d’autorités gouvernementales. Si de nombreuses interrogations portent sur une loi américaine de 2018 connue sous le nom de Clarifying Lawful Overseas Use of Data Act (CLOUD Act), cette loi n’a en réalité octroyé aucune nouvelle prérogative au gouvernement américain pour contraindre les fournisseurs à divulguer des données. Elle prévoit des garde-fous juridiques essentiels pour protéger les données des utilisateurs.
Replaçons cette question en perspective : depuis que nous avons commencé à publier des rapports sur les demandes d’informations en 2020, aucune demande n’a abouti à la divulgation auprès du gouvernement américain, de données d’entreprises ou de gouvernements stockées hors des États-Unis. Notre engagement à protéger les données de nos clients repose sur plusieurs niveaux de protection juridique, technique et opérationnelle. A titre d’exemple, les principaux produits et services d’AWS ont été conçus by design de manière à empêcher quiconque, hormis le client et les personnes autorisées par celui-ci, d’accéder à ses données. Ainsi, toute autorité gouvernementale souhaitant accéder aux données d’un client doit en faire la demande directement auprès de celui-ci. En outre, la législation américaine prévoit elle-même de nombreuses protections statutaires qui limitent la possibilité qu’AWS soit contrainte de divulguer des données d’entreprises ou de gouvernements. Le Département de la Justice américain (DOJ) a mis en place des mesures de protections supplémentaires au cours des huit dernières années d’un point de vue opérationnel.
Dans ce contexte, nous souhaitons revenir sur certaines idées reçues courantes à propos du CLOUD Act et apporter des éclaircissements sur l’impact – ou l’absence d’impact – de cette loi sur les clients d’AWS dans le monde entier. Afin d’aider nos clients et partenaires à mieux appréhender ce sujet, nous avons également complété notre FAQ sur le CLOUD Act.
Fait n°1 : Le CLOUD Act n’accorde pas au gouvernement américain un accès illimité ou automatique aux données stockées dans le cloud
Le CLOUD Act a été adopté pour répondre aux défis rencontrés par les autorités judiciaires dans l’obtention des données stockées à l’étranger dans le cadre d’enquêtes transfrontalières sur des crimes graves, allant du terrorisme et des crimes violents à l’exploitation sexuelle d’enfants et à la cybercriminalité. Le CLOUD Act a principalement permis aux États-Unis de conclure des accords exécutifs réciproques avec des partenaires étrangers de confiance. Ces accords visent à faciliter l’accès aux preuves électroniques dans le cadre d’enquêtes sur des crimes graves, indépendamment de la localisation de ces preuves. Pour ce faire, le CLOUD Act lève certaines restrictions prévues par la législation américaine.
De nombreux gouvernements s’appuient sur leurs lois nationales pour exiger des fournisseurs assujettis à ces lois qu’ils divulguent des données électroniques sous leur contrôle, indépendamment du lieu de stockage de ces données. De même, le CLOUD Act a clarifié que les autorités judiciaires américaines pouvaient s’appuyer sur les dispositifs légaux existants, tel qu’un mandat de perquisition autorisé par un tribunal, pour exiger d’un fournisseur la divulgation de données sous son contrôle, indépendamment de leur localisation. Les accords exécutifs bilatéraux permettent la mise en œuvre effective de ces accords de réciprocité, encadrée par des garanties procédurales et juridiques rigoureuses.
L’accès à des données en vertu de la loi américaine est loin d’être illimité ou automatique, et les autorités judiciaires doivent respecter des conditions juridiques strictes. En vertu de la loi américaine, il est de fait interdit aux fournisseurs de divulguer des données au gouvernement américain, sauf exception spécifique. Pour contraindre un fournisseur à la divulgation de données, les autorités judiciaires doivent démontrer devant un juge fédéral indépendant qu’il existe des indices graves et concordants relatifs à un crime et qu’il est probable que des éléments de preuve de ce crime se trouvent dans le périmètre visé par la perquisition (par exemple, un compte électronique spécifique tel qu’une messagerie). La mise en œuvre de cette exception doit s’appuyer sur des éléments factuels précis et vérifiables.
Chaque mandat de perquisition est soumis à cette évaluation stricte de la présence d’indices graves et concordants, qui doit reposer sur des faits crédibles, respecter les critères de spécificité et de légalité, être autorisé par un juge indépendant et satisfaire aux conditions de compétence matérielle et juridictionnelle. En mai 2023, le DOJ a par ailleurs publié des directives imposant aux procureurs qui recherchent des preuves localisées à l’étranger d’obtenir préalablement l’autorisation du Bureau des Affaires Internationales (OIA) avant d’obtenir toute ordonnance. La politique du DOJ concernant les preuves situées à l’étranger reconnaît que chaque État adopte des lois pour protéger sa souveraineté. L’OIA intervient pour traiter ces questions et accompagner les procureurs dans l’identification des mécanismes appropriés d’obtention des preuves.
Fait n°2 : Depuis la mise en place du suivi statistique, AWS n’a divulgué aucune donnée d’entreprise ou de gouvernement en vertu du CLOUD Act
AWS applique des procédures strictes pour traiter les demandes des autorités judiciaires de tout pays, en vérifiant leur légitimité et leur conformité à la réglementation applicable. Si AWS reconnaît les besoins légitimes des autorités judiciaires dans leurs enquêtes sur les activités criminelles et terroristes, les autorités doivent respecter les mesures de protection juridiques encadrant ces enquêtes. En effet, notre politique est claire : nous ne divulguons pas les données des clients en réponse à une demande gouvernementale, sauf si nous en sommes contraints par une ordonnance juridiquement valide et contraignante. Nous avons pris cet engagement publiquement dans nos conditions juridiques.
Nous contestons les demandes gouvernementales qui s’avèrent illégales, disproportionnées ou inappropriées (notamment celles qui porteraient atteintes aux droits fondamentaux des individus). Pour les demandes concernant les données d’entreprises clientes, nous mettons tout en œuvre pour rediriger les autorités judiciaires vers le client et l’informer lorsque la loi le permet. En cas d’obligation de divulgation des données d’un client, nous l’en informons au préalable pour lui permettre de se prémunir contre cette divulgation, sauf interdiction par la loi. Si, après ces étapes, AWS reste contrainte de divulguer des données client et dispose de la capacité technique de le faire (ce qui, comme mentionné précédemment, est rarement le cas), nous limitons la divulgation au strict minimum requis par la procédure judiciaire.
Conformément à notre politique de redirection des autorités judiciaires vers les clients, le département des crimes informatiques et de la propriété intellectuelle du DOJ américain a également émis des lignes directrices recommandant aux procureurs de privilégier l’obtention des données directement auprès de l’entreprise concernée, plutôt qu’auprès du fournisseur cloud hébergeant ces données.
Une preuve tangible de l’efficacité de nos mesures et des exigences juridiques rigoureuses inscrites dans la loi : depuis le début du suivi de cette statistique en 2020, AWS n’a divulgué au gouvernement américain aucune donnée de client d’entreprise ou de gouvernement stockée hors des États-Unis. Ce bilan résulte des garanties techniques offertes par AWS, des conditions juridiques strictes prévues par la législation américaine, des politiques mises en œuvre par le DOJ, et de la nature des enquêtes des autorités judiciaires qui ciblent principalement la collecte de preuves électroniques issues de comptes de particuliers.
Fait n°3 : Le CLOUD Act ne s’applique pas uniquement aux entreprises dont le siège est situé aux États-Unis, mais à toute entreprise exerçant une activité commerciale aux États-Unis
Le CLOUD Act s’applique à l’ensemble des fournisseurs de services de communication électronique ou de services informatiques à distance qui exercent une activité ou disposent d’une présence juridique aux États-Unis, indépendamment de la localisation de leur siège social. Par conséquent, les fournisseurs de services cloud européens ayant des activités aux États-Unis sont également assujettis aux dispositions de cette loi. À titre d’exemple, OVHcloud, entreprise française de services cloud présente aux États-Unis, précise dans sa FAQ relative au CLOUD Act qu’”OVHcloud se conformera aux demandes légales des autorités publiques. En vertu du CLOUD Act, cela pourrait inclure des données stockées en dehors des États-Unis.” De même, d’autres fournisseurs de cloud dont le siège est situé dans l’Union européenne ou ailleurs exercent également des activités aux États-Unis.
Fait n°4 : Les principes du CLOUD Act s’inscrivent dans le cadre du droit international et des législations nationales
Le CLOUD Act n’a pas introduit de nouveau concept juridique concernant l’accès aux données électroniques dans le cadre d’enquêtes pénales. De nombreux États exigent la divulgation de données clients quel que soit leur lieu de stockage en réponse à des procédures judiciaires impliquant des crimes graves. La loi britannique Crime (Overseas Production Orders) Act, par exemple, permet aux autorités judiciaires britanniques d’obtenir des données électroniques stockées hors du Royaume-Uni dans le cadre d’une enquête pénale. Selon un document du DOJ américain publié en 2024, plusieurs États membres de l’Union européenne, dont la Belgique, le Danemark, la France, l’Irlande et l’Espagne, disposent d’exigences similaires. En réalité, depuis 2023, la majorité des demandes d’accès aux données reçues par AWS émanent d’autorités situées en dehors des États-Unis.
Ce principe est également inscrit dans la Convention de Budapest sur la cybercriminalité, premier traité international visant à renforcer la coopération en matière d’enquêtes sur la cybercriminalité. Par ailleurs, le Règlement européen e-Evidence (2023/1543), adopté en août 2023, habilite les États membres à “ordonner à un fournisseur de services de produire ou de conserver des preuves électroniques, quelle que soit la localisation des données.” Le RGPD prévoit également la possibilité de transferts de données personnelles en réponse aux demandes contraignantes de pays tiers, sous réserve d’une base juridique appropriée et d’un mécanisme de transfert ou d’une dérogation (voir les Lignes directrices 02/2024 du Comité européen de la protection des données sur l’Article 48).
AWS soutient la conclusion d’accords de coopération bilatéraux dans le cadre du CLOUD Act, notamment entre les États-Unis et l’Union européenne, ainsi qu’entre les États-Unis et le Canada. Ces accords sont essentiels pour résoudre les conflits potentiels de lois et permettre des enquêtes efficaces sur les crimes graves afin d’améliorer la sécurité publique, tout en s’appuyant sur les garanties procédurales et juridiques substantielles déjà prévues par la législation américaine.
Fait n°5 : Le CLOUD Act n’a pas d’impact sur les dispositifs techniques et les mesures de contrôle qu’AWS met à disposition de ses clients pour prévenir tout accès non autorisé à leurs données
AWS ne peut répondre aux demandes judiciaires de communication de données que lorsqu’elle dispose de la capacité technique de le faire. Or, AWS a développé de nombreux produits et services garantissant qu’aucun tiers – y compris ses propres employés – ne peut accéder aux données des clients. Les clients d’AWS ont également à leur disposition un ensemble de dispositifs techniques et de mesures de contrôle complémentaires pour protéger leurs données. À titre d’exemple, la plupart des principaux systèmes et services d’AWS sont conçus sans aucune possibilité d’accès technique, selon le principe d’absence d’accès pour les opérateurs (zero operator access). Cela signifie que les services ne disposent d’aucun moyen technique permettant aux opérateurs d’AWS d’accéder aux données des clients en réponse à une demande judiciaire.
Le système AWS Nitro, qui est à la base des services informatiques AWS, utilise des composants matériels et logiciels spécifiques pour protéger les données de tout accès externe lors de leur traitement sur Amazon Elastic Compute Cloud (Amazon EC2). En établissant une barrière physique et logique renforcée, le système Nitro est conçu de sorte qu’aucune personne non autorisée – y compris les opérateurs d’AWS – ne peut accéder aux charges de travail des clients sur EC2. L’architecture du système Nitro a été certifiée par NCC Group, organisme indépendant en cybersécurité. Ces dispositifs de contrôle empêchant tout accès de nos opérateurs sont si essentiels au système Nitro que nous les avons intégrés dans nos Conditions de Service AWS, offrant ainsi une garantie contractuelle supplémentaire à l’ensemble de nos clients.
Nous proposons également à nos clients des fonctionnalités et des mécanismes de chiffrement des données, qu’elles soient en transit, au repos ou en mémoire. L’ensemble des services AWS intègrent le chiffrement, la majorité permettant également le chiffrement via des clés gérées par le client et inaccessibles à AWS. AWS Key Management Service (AWS KMS) est le premier système de gestion de clés natif au cloud, hautement évolutif, à obtenir la certification FIPS 140-3 Niveau 3. Concrètement, AWS propose un chiffrement de niveau supérieur où les clients conservent le contrôle exclusif de l’accès aux clés.
Poursuivre notre obsession client
Chez AWS, notre approche centrée sur le client guide l’ensemble de nos actions, de la conception de nos services à la protection de vos données. La confiance que vous nous accordez repose sur notre transparence, la robustesse de nos dispositifs techniques de contrôle et notre détermination à défendre vos intérêts.
C’est dans cet esprit que nous avons établi une communication claire et transparente sur notre traitement des demandes d’accès aux données émanant des autorités, notamment concernant l’application du CLOUD Act, ainsi que sur les différents niveaux de protection – juridiques, opérationnels et techniques – mis en œuvre pour sécuriser vos données.
Nous vous invitons à approfondir vos connaissances de ce sujet en consultant notre FAQ détaillée sur le CLOUD Act.
Nous poursuivrons nos efforts d’innovation, à votre service, en développant de nouvelles fonctionnalités et de nouveaux services vous garantissant la maîtrise de vos données, tout en maintenant nos engagements en matière de confidentialité et de sécurité.
A propos de l’auteur
Bob Kimball occupe le poste de Chief Regulatory Officer après avoir été General Counsel d’AWS. Dans ses fonctions actuelles, il pilote les questions réglementaires mondiales d’AWS, travaillant en étroite collaboration avec les régulateurs et les clients sur des enjeux tels que l’IA, la souveraineté numérique, l’énergie et d’autres sujets clés liés à l’exploitation des infrastructures et services cloud.
German version
Fünf Fakten zur tatsächlichen Funktionsweise des CLOUD Act
Bei Amazon Web Services (AWS) haben Kundendatenschutz und -sicherheit höchste Priorität. Wir bieten unseren Kunden branchenführenden Datenschutz und erstklassige Sicherheit bei der Nutzung der AWS Cloud – weltweit. In den vergangenen Monaten haben wir ein gestiegenes Interesse zum Umgang mit behördlichen Datenanfragen festgestellt. Viele dieser Fragen beziehen sich auf ein US-amerikanisches Gesetz aus dem Jahr 2018, den Clarifying Lawful Overseas Use of Data Act (CLOUD Act). Tatsächlich hat der CLOUD Act der US-Regierung keinerlei neue Befugnisse eingeräumt, Daten von Anbietern anzufordern, sondern schafft vielmehr wichtige rechtliche Leitplanken zum Schutz von Inhalten.
Um diese Thematik in den richtigen Kontext zu setzen: Seit wir 2020 mit der statistischen Erfassung begonnen haben, gab es keine Datenanfragen an AWS, die zur Offenlegung von außerhalb der USA gespeicherten Kundeninhalten von Unternehmens- oder Regierungsdaten gegenüber der US-Regierung geführt haben. Unser Engagement zum Schutz von Kundendaten wird durch mehrere Ebenen rechtlichen, technischen und operativen Schutzes untermauert. AWS hat beispielsweise seine Kernprodukte und -services so konzipiert, dass nur Kunden selbst und die von ihnen autorisierten Personen auf die Kundeninhalte zugreifen können. In diesen Fällen müsste jede Regierung, die Zugriff auf Kundeninhalte wünscht, diese Daten direkt beim Kunden anfragen. Darüber hinaus bietet das US-Recht selbst zahlreiche gesetzliche Schutzmaßnahmen, die das Risiko verringern, dass AWS zur Offenlegung von Unternehmens- oder Regierungsdaten verpflichtet werden könnte. Das US-Justizministerium (DOJ) hat in den letzten acht Jahren zusätzliche operative Schutzmaßnahmen implementiert.
Vor diesem Hintergrund möchten wir einige häufige Missverständnisse über den CLOUD Act ansprechen und Klarheit darüber schaffen, wie sich dieses Gesetz auf AWS Kunden weltweit auswirkt – oder eben nicht auswirkt. Außerdem erweitern wir unsere FAQ zum CLOUD Act, um unseren Kunden und Partnern den Umgang mit diesem Thema zu erleichtern.
Fakt 1: Der CLOUD Act gewährt der US-Regierung keinen uneingeschränkten oder automatischen Zugriff auf in der Cloud gespeicherte Daten
Der CLOUD Act wurde verabschiedet, um Herausforderungen zu bewältigen, denen Strafverfolgungsbehörden bei der Beschaffung von im Ausland gespeicherten Daten in grenzüberschreitenden Ermittlungen zu schweren Straftaten begegneten. Dazu gehören Terrorismus und Gewaltverbrechen bis hin zu sexueller Ausbeutung von Kindern und Cyberkriminalität. Der CLOUD Act ermöglicht es den USA in erster Linie, gegenseitige Vollzugsvereinbarungen mit vertrauenswürdigen ausländischen Partnern zu schließen, um Zugang zu elektronischen Beweismitteln für Ermittlungen bei schweren Straftaten zu erhalten, unabhängig vom Speicherort der Beweise, indem Sperrgesetze nach US-Recht aufgehoben wurden. Viele Regierungen stützen sich auf nationale Gesetze, um von Anbietern innerhalb ihres Zuständigkeitsbereichs die Offenlegung elektronischer Daten unter der Kontrolle der Unternehmen zu verlangen, unabhängig davon, wo die Daten gespeichert sind. In ähnlicher Weise stellte der CLOUD Act klar, dass US-Strafverfolgungsbehörden bestehende Befugnisse wie einen gerichtlich genehmigten Durchsuchungsbeschluss nutzen können, um Daten unter der Kontrolle eines Anbieters anzufordern, unabhängig vom Speicherort der Daten; die Vollzugsvereinbarungen ermöglichen die Wirksamkeit dieser gegenseitigen Gesetze, unterstützt durch strenge verfahrensrechtliche und materielle Schutzmaßnahmen.
Der Zugriff auf Daten nach US-Recht ist bei weitem nicht uneingeschränkt oder automatisch möglich, und Strafverfolgungsbehörden müssen strenge rechtliche Standards erfüllen. Nach US-Recht ist es Anbietern sogar untersagt, Daten ohne rechtliche Ausnahmeregelung an die US-Regierung weiterzugeben. Um einen Anbieter zur Offenlegung von Inhaltsdaten zu verpflichten, muss die Strafverfolgungsbehörde einen unabhängigen Bundesrichter davon überzeugen, dass ein hinreichender Verdacht bezüglich einer bestimmten Straftat besteht und dass Beweise für diese Straftat am zu durchsuchenden Ort gefunden werden (das heißt in einem bestimmten elektronischen Konto wie einem E-Mail-Account). Dieser Rechtsstandard muss durch konkrete und vertrauenswürdige Fakten belegt werden. Jeder Durchsuchungsbeschluss muss diese strenge Prüfung des hinreichenden Verdachts anhand glaubwürdiger Fakten, Spezifität und Rechtmäßigkeit bestehen, muss von einem unabhängigen Richter genehmigt werden und muss die Anforderungen hinsichtlich Umfang und Zuständigkeit erfüllen. Im Mai 2023 hat das DOJ außerdem eine Richtlinie erlassen, wonach Staatsanwälte, die nachweislich im Ausland gespeicherte Beweismittel anfordern, vor Erhalt einer entsprechenden Anordnung die Genehmigung des Office of International Affairs (OIA) des Ministeriums einholen müssen. Die DOJ-Richtlinie zu Beweismitteln im Ausland weist darauf hin, dass jede Nation Gesetze zum Schutz ihrer Souveränität erlässt; das OIA arbeitet daran, diesbezügliche Fragen zu klären und Staatsanwälte bei der Auswahl eines geeigneten Mechanismus zur Sicherung von Beweismitteln zu unterstützen.
Fakt 2: AWS hat seit Beginn der statistischen Erfassung keine Kundeninhalte von Unternehmens- oder Regierungskundendaten aufgrund des CLOUD Act offengelegt
AWS verfügt über strenge Verfahren zur Bearbeitung von Anfragen von Strafverfolgungsbehörden aus allen Ländern, um deren Legitimität zu prüfen und sicherzustellen, dass sie geltendem Recht entsprechen. AWS erkennt die legitimen Bedürfnisse von Strafverfolgungsbehörden bei der Untersuchung krimineller und terroristischer Aktivitäten an, aber diese müssen die rechtlichen Schutzmaßnahmen für solche Ermittlungen beachten. Wir geben Kundendaten auf keinerlei behördliche Anfragen heraus, es sei denn, wir sind dazu durch eine rechtlich gültige und verbindliche Anordnung verpflichtet. Dies haben wir in unseren rechtlichen Bedingungen öffentlich zugesichert. Darüber hinaus werden wir behördliche Anfragen anfechten, die gegen das Gesetz verstoßen, zu weitreichend oder anderweitig unangemessen sind (beispielsweise, wenn eine solche Anfrage die Grundrechte von Personen verletzen würde). Wenn wir solche Anfragen nach Inhalten von Unternehmenskunden erhalten, unternehmen wir alle angemessenen Anstrengungen, um Strafverfolgungsbehörden an den Kunden zu verweisen und den Kunden zu benachrichtigen, wenn dies rechtlich zulässig ist. Wenn wir zur Offenlegung von Kundeninhalten verpflichtet sind, benachrichtigen wir die Kunden vor der Offenlegung, um ihnen die Möglichkeit zu geben, sich gegen die Offenlegung zu schützen, sofern dies nicht gesetzlich untersagt ist. Wenn AWS nach Ausschöpfung dieser Schritte weiterhin zur Offenlegung von Kundendaten verpflichtet ist und wir die technische Möglichkeit dazu haben (was, wie oben beschrieben, in vielen Fällen nicht der Fall ist), legen wir nur das zur Erfüllung des rechtlichen Verfahrens unbedingt Notwendige offen.
In Übereinstimmung mit unserer Richtlinie, Strafverfolgungsbehörden an die Kunden zu verweisen, hat auch die Computer Crime and Intellectual Property Section des DOJ Leitlinien herausgegeben, die Staatsanwälte anweisen, Daten grundsätzlich direkt von einem Unternehmen anzufordern, wie beispielsweise von einem Unternehmen, das Daten bei einem Cloud-Anbieter speichert, und nicht vom Anbieter selbst.
Ein deutlicher Beleg für die Wirksamkeit unserer Maßnahmen und der strengen gesetzlichen Anforderungen ist die Tatsache, dass AWS seit Beginn der statistischen Erfassung im Jahr 2020 keine außerhalb der USA gespeicherten Kundeninhalte von Unternehmens- oder Regierungskundendaten an die US-Regierung weitergegeben hat. Diese Bilanz spiegelt die technischen Schutzmaßnahmen von AWS, die robusten rechtlichen Schutzmaßnahmen im US-Recht, die vom DOJ umgesetzten Richtlinien und die Art der strafrechtlichen Ermittlungen wider, die sich hauptsächlich auf die Sammlung elektronischer Beweise aus Verbraucherkonten konzentrieren.
Fakt 3: Der CLOUD Act gilt nicht nur für Unternehmen mit Hauptsitz in den USA – er gilt für alle Anbieter, die Geschäfte in den Vereinigten Staaten tätigen
Der CLOUD Act gilt für alle Anbieter von elektronischen Kommunikationsdiensten oder Remote-Computing-Diensten, die in den USA tätig sind oder dort eine rechtliche Präsenz haben – unabhängig vom Standort ihres Hauptsitzes. Beispielsweise unterliegen auch Cloud-Anbieter mit Hauptsitz in Europa, die Geschäfte in den USA tätigen, den Anforderungen des Gesetzes. OVHcloud, ein Cloud-Service-Anbieter mit Hauptsitz in Frankreich, der in den USA tätig ist, vermerkt auf seiner CLOUD Act FAQ-Seite, dass “OVHcloud rechtmäßigen Anfragen von Behörden nachkommen wird. Im Rahmen des CLOUD Act könnte dies auch Daten einschließen, die außerhalb der Vereinigten Staaten gespeichert sind.” Ähnlich verhält es sich mit anderen Cloud-Anbietern mit Hauptsitz in der EU und anderswo, die ebenfalls in den USA tätig sind.
Fakt 4: Die Grundsätze des CLOUD Act stehen im Einklang mit internationalem Recht und den Gesetzen anderer Länder
Der CLOUD Act hat keine neue Rechtsposition bezüglich des Umfangs elektronischer Daten eingeführt, die im Rahmen legitimer strafrechtlicher Ermittlungen offengelegt werden müssen. Viele Länder verlangen die Offenlegung von Kundendaten, unabhängig vom Speicherort, als Reaktion auf rechtliche Verfahren im Zusammenhang mit schweren Straftaten. Der britische Crime (Overseas Production Orders) Act beispielsweise ermöglicht es britischen Strafverfolgungsbehörden, im Zusammenhang mit strafrechtlichen Ermittlungen auf außerhalb des Vereinigten Königreichs gespeicherte elektronische Daten zuzugreifen. Laut einer Einreichung des US-DOJ von 2024 haben mehrere EU-Mitgliedstaaten, darunter Belgien, Dänemark, Frankreich, Irland und Spanien, ähnliche Anforderungen. Tatsächlich kommt seit 2023 die Mehrheit der Strafverfolgungsanfragen, die AWS erhält, von Behörden außerhalb der Vereinigten Staaten.
Dieses Konzept ist auch in der Budapest-Konvention zur Cyberkriminalität verankert, dem ersten internationalen Vertrag zur Verbesserung der Zusammenarbeit bei der Untersuchung von Cyberkriminalität. Darüber hinaus ermächtigt die EU-Verordnung e-Evidence, 2023/1543, die im August 2023 verabschiedet wurde, die Mitgliedstaaten dazu, “einen Dienstanbieter anzuweisen, elektronische Beweismittel unabhängig vom Standort der Daten zu erstellen oder zu sichern”. Die DSGVO erlaubt ebenfalls die Übermittlung personenbezogener Daten als Reaktion auf verpflichtende Offenlegungsanfragen aus Drittländern – vorausgesetzt, die betreffende Partei kann sich auf eine geeignete Rechtsgrundlage und ein Übertragungsinstrument oder eine Ausnahmeregelung berufen (siehe die aktuellen EDSA Leitlinien 02/2024 zu Artikel 48).
AWS setzt sich dafür ein, dass Regierungen gegenseitige Vollzugsvereinbarungen im Rahmen des CLOUD Act abschließen, einschließlich zwischen den USA und der Europäischen Union sowie den USA und Kanada. Wir glauben, dass diese Vereinbarungen wichtig sind, um potenzielle Gesetzeskonflikte endgültig zu lösen und eine effektive Untersuchung schwerer Straftaten zur Förderung der öffentlichen Sicherheit zu ermöglichen. Dabei werden die bereits bestehenden starken materiell- und verfahrensrechtlichen Schutzmaßnahmen nach US-Recht anerkannt.
Fakt 5: Der CLOUD Act beschränkt nicht die technischen Maßnahmen und operativen Kontrollen, die AWS seinen Kunden zum Schutz vor unbefugtem Zugriff auf Kundendaten anbietet
Wir können auf rechtliche Datenanfragen nur dann reagieren, wenn wir die technische Möglichkeit dazu haben. AWS verfügt über eine Reihe von Produkten und Services, die sicherstellen, dass niemand – nicht einmal Mitarbeiter:innen von AWS – auf Kundeninhalte zugreifen können. AWS Kunden verfügen auch über eine Reihe zusätzlicher technischer Maßnahmen und operativer Kontrollen, um den Zugriff auf Daten zu verhindern. Beispielsweise sind viele der AWS Kernsysteme und Services mit Zero-Operator-Zugriff konzipiert, was bedeutet, dass die Services keine technischen Möglichkeiten für AWS Mitarbeiter:innen bieten, auf Kundendaten als Reaktion auf eine rechtliche Anfrage zuzugreifen.
Das AWS Nitro System, das die Grundlage der AWS Rechendienstleistungen bildet, verwendet spezialisierte Hardware und Software, um Daten während der Verarbeitung auf Amazon Elastic Compute Cloud (Amazon EC2) vor externem Zugriff zu schützen. Durch eine starke physische und logische Sicherheitsgrenze ist Nitro so konzipiert, dass keine unbefugte Person – nicht einmal AWS Mitarbeiter:innen – auf Workloads von Kunden auf EC2 zugreifen kann. Das Design des Nitro Systems wurde von der NCC Group, einem unabhängigen Cybersicherheitsunternehmen, validiert. Die Kontrollen, die den Betreiberzugriff verhindern, sind für das Nitro System so grundlegend, dass wir sie in unsere AWS Servicebedingungen aufgenommen haben, um allen unseren Kunden eine zusätzliche vertragliche Zusicherung zu geben.
Wir bieten Kunden auch Funktionen und Kontrollen zur Verschlüsselung von Daten, sei es während der Übertragung, im Ruhezustand oder im Arbeitsspeicher. Alle AWS Services unterstützen bereits Verschlüsselung, wobei die meisten auch die Verschlüsselung mit kundenverwalteten Schlüsseln unterstützen, die für AWS nicht zugänglich sind. Der AWS Key Management Service (AWS KMS) ist das erste hochskalierbare, Cloud-native Schlüsselverwaltungssystem mit FIPS 140-3 Level 3-Zertifizierung. Vereinfacht ausgedrückt bedeutet dies, dass AWS eine äußerst starke Verschlüsselung anbietet, bei der unsere Kunden kontrollieren, wer einen Schlüssel erhält.
Fortsetzung unserer Kundenorientierung
Bei AWS bestimmt unser kundenorientierter Ansatz alles, was wir tun – von der Gestaltung unserer Services bis zum Schutz Ihrer Daten. Wir verstehen, dass Ihr Vertrauen durch Transparenz, starke technische Kontrollen und unermüdlichen Einsatz für Ihre Interessen verdient wird. Deshalb haben wir klar kommuniziert, wie wir mit behördlichen Datenanfragen umgehen, einschließlich der Auswirkungen des CLOUD Act, und der mehrschichtigen Schutzmaßnahmen – rechtlich, operativ und technisch – zum Schutz Ihrer Daten.
Wir ermutigen Sie, mehr über dieses wichtige Thema zu in unseren erweiterten CLOUD Act FAQs zu lesen. Wir werden weiterhin in Ihrem Interesse innovativ sein, neue Funktionen und Services entwickeln, die Ihnen die Kontrolle über Ihre Daten geben, und unser Engagement für höchste Datenschutz- und Sicherheitsstandards aufrechterhalten.
Über den Autor
Bob Kimball ist Chief Regulatory Officer und ehemaliger General Counsel bei AWS. In seiner aktuellen Position ist Bob ein AWS-Experte für globale regulatorische Fragen und arbeitet eng mit Aufsichtsbehörden und Kunden zu Themen wie KI, digitale Souveränität, Energie und anderen Schlüsselthemen zusammen, die den Betrieb von Cloud-Infrastruktur und -Services betreffen.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Last month, we announced new sovereign controls and governance structure for the AWS European Sovereign Cloud. The AWS European Sovereign Cloud is a new, independent cloud for Europe, designed to help customers meet their evolving sovereignty needs, including stringent data residency, operational autonomy, and resiliency requirements. Launching by the end of 2025, the AWS European Sovereign Cloud will be entirely located within the European Union (EU) and operate as an independent cloud for Europe. Last month, we announced plans to launch a dedicated European certificate authority (CA), or trust service provider, to support autonomous trust service operations within the AWS European Sovereign Cloud.
We are actively building out the first AWS Region of the AWS European Sovereign Cloud in the state of Brandenburg, Germany. We are on track for launch and AWS services are being deployed, configured, and tested for autonomous operations in the AWS European Sovereign Cloud. The AWS European Sovereign Cloud infrastructure will be physically and logically separate from other Regions. We designed the AWS European Sovereign Cloud to have no critical dependencies on non-EU infrastructure. Everything needed to operate the AWS European Sovereign Cloud is in the EU: the talent, the technology, the infrastructure, and the leadership. In addition to independent infrastructure, there will be zero operational control outside of EU borders. Only AWS employees, residing in the EU, will control day-to-day operations, including access to data centers, technical support, and customer service for the AWS European Sovereign Cloud.
For the first time, we will provide a dedicated sovereign European trust service provider (EU-TSP). This EU-TSP will autonomously operate its own CA key materials and perform certificate issuance functions within the AWS European Sovereign Cloud. A trust service provider is an entity that manages the policies and operations for a set of root and subordinate certificate authorities. A root CA is a cryptographic building block and root of trust upon which end entity certificates can be issued. It represents a private key for signing (issuing) certificates and a root certificate that identifies the root CA and binds the private key to the name of the CA. In short, the EU-TSP is an autonomous trust service provider in Europe, for Europe.
The EU-TSP will be the public root of trust for the AWS European Sovereign Cloud, helping to maintain the confidentiality and integrity of network communications. The EU-TSP will provide the default CA used by AWS service endpoints, AWS Certificate Manager (ACM), and ACM integrated services. For AWS European Sovereign Cloud customers, this means that even in the event of a material loss of connectivity outside of the EU, the EU-TSP will continue to provide trust services autonomously.
We recently completed the cryptographic key signing ceremony for our EU-TSP at a secure EU location, witnessed by external, third-party auditors. The resulting root CAs have been submitted for inclusion to popular web browsers used by AWS customers. This EU-TSP will be operated in accordance with the requirements of the Certificate Authority/Browser Forum. All the key material for the EU-TSP is located within EU borders, and only EU residents have the ability to operate, control, or reconfigure the EU-TSP.
To maintain verifiable trust, we will engage independent EU-based auditors to assure the EU-TSP controls are designed appropriately, operate effectively, and can help customers satisfy their compliance obligations. We will make the audit reports publicly available.
The EU-TSP will be active and providing autonomous trust services when the AWS European Sovereign Cloud launches at the end of 2025. To learn more, visit AWS European Sovereign Cloud.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Stifel Financial Corp. is an American multinational independent investment bank and financial services company, founded in 1890 and headquartered in downtown St. Louis, Missouri. Stifel offers securities-related financial services in the United States and Europe through several wholly owned subsidiaries. Stifel provides both equity and fixed income research and is the largest provider of US equity research.
In this post, we show you how Stifel implemented a modern data platform using AWS services and open data standards, building an event-driven architecture for domain data products while centralizing the metadata to facilitate discovery and sharing of data products.
Stifel’s modern data platform use case
Stifel envisioned a data platform that delivers accurate, timely, and properly governed data, providing consistency throughout the organization whenever users access the information. This approach showed limitations as the data complexity increased, data volumes grew, and demand for quick, business-driven insights rose. These challenges are encountered by financial institutions worldwide, leading to a reassessment of traditional data management practices. Under the federated governance model, Stifel developed a modern data strategy based on the following objectives:
Managing ingestion and metadata
Creating source-aligned data products complying with Stifel business streams
Integrating source-aligned data products from other domains (Stifel business units)
Producing consumer-aligned data products for specific business purposes
Publishing data products to a centralized data catalog
Some of the Stifel challenges highlighted in the preceding list required building a data platform that can:
Boost agility by democratizing data, thus reducing time to market and enhancing the customer experience
Improve data quality and trust in the data
Standardize tools and eliminate the shadow information technology (IT) culture to increase scalability, reduce risk, and minimize operational inefficiencies
Following the federated governance model, Stifel has organized its domain structure to provide autonomy to various functional teams while preserving the core values of data mesh. The following diagram depicts a high-level architecture of the data mesh implementation at Stifel.
Each data domain has the flexibility to create data products that can be published to the centralized catalog, while maintaining the autonomy for teams to develop data products that are exclusively accessible to teams within the domain. These products aren’t available to others until they are deemed ready for broader enterprise use. Domains have the freedom to decide which data they want to share. They can either:
Make their data products visible to everyone through the central catalog
Keep their data products visible only within their own domain
By implementing an event-driven domain architecture, organizations can achieve significant business advantages while positioning themselves for future growth and innovation. Stifel data products refreshes were dependent on data assets with variable cadence. Event-driven architecture enables real-time or near real-time updates by allowing data products to automatically respond to changes in underlying data assets as they occur, rather than relying on fixed batch schedules that might miss critical updates or waste resources on unnecessary refreshes. The key is to carefully plan the implementation and make sure of alignment with business objectives while considering both technical and organizational factors. This architecture style particularly suits organizations that:
Need real-time processing capabilities
Have complex domain interactions
Require high scalability
Want to improve business agility
Need better system integration
Are pursuing digital transformation
The following are some of the key AWS Services that helped Stifel to build their modern data platform.
AWS Glue is a serverless data integration service that’s used for data processing to build data assets and data products in the domains. Data is also cataloged in AWS Glue Catalog, making it straightforward to discover and query with supported engines.
Amazon EventBridge provides a scalable and flexible serverless event bus that facilitates seamless communication between different domains and services. By using EventBridge, Stifel was able to implement a publish-subscribe model where domain events can be emitted, filtered, and routed to appropriate consumers based on configurable rules. EventBridge supports custom event buses for domain-specific events, enabling clear separation of concerns and improved manageability.
AWS Lake Formation helped in providing centralized security, governance, and catalog capabilities while preserving domain autonomy in data product creation and management. With Lake Formation, data domains were able to maintain their independent data products within a federated structure while enforcing consistent access controls, data quality standards, and metadata management across the organization.
The following diagram illustrates the data mesh architecture that Stifel uses to build a domain-driven architecture. In this system, various domains create data products and share them with other domains through a central governance account that uses Lake Formation.
Let’s look at some of the key design components that are being used to enable and implement data mesh and event driven design
Data ingestion framework
The data ingestion framework consists of several processor modules that are built using several AWS services and metadata driven architecture. The following diagram shows the architecture of the raw data ingestion framework.
The framework gets raw data files from both internal Stifel systems and third-party data sources. These files are processed and stored in a raw data ingestion account on Amazon S3 in open table format Apache Hudi. This stored data is then shared with different parts of the organization, called data domains. Each domain can use this shared data to create their own data products.
As a file (in CSV, XML, JSON and custom formats) lands into the landing bucket, an Amazon S3 event notification is created and placed in an Amazon Simple Queue Service (Amazon SQS)queue. The Amazon SQS queue triggers an AWS Lambda function and saves the metadata (such as the name of the file, date and time the file was received, and the file size) to a file audit data store (Amazon Aurora PostgreSQL-Compatible Edition).
An EventBridge time scheduler invokes an AWS Step Functions workflow at pre-determined intervals. The Step Functions workflow orchestrates the batch ingestion from raw to staging layer.
The Step Functions workflow orchestrates a set of Lambda functions to get the list of unprocessed raw files from the audit data store and create batches of raw files to process them in parallel. The Step Functions workflow then triggers parallel AWS Glue jobs that process each batch of raw files.
Each raw file is validated for any data quality checks and the data is saved to staging tables in Hudi format. Any errors encountered are logged into an audit table and a notification is generated for support team. For all successfully processed raw files, the file status is updated to PROCESSED and logged into an audit table.
After the Hudi table is updated, a data refresh event is sent to EventBridge and then passed to the Central Mesh Account. The Central Mesh Account forwards these events to the data domains to notify them that the raw tables are refreshed, allowing the data domains to use this data for creating their own data products.
Event driven data product refresh
The Stifel data lake is based on a data mesh architecture where several data producers share data across data domains. A mechanism is needed to alert consumers who depend on other data producers’ data products when those source data products are refreshed, so that the consumers can update their own data products accordingly. The following diagram describes the technical architecture of event-based data processing. The central governance account acts as the central event bus, which receives all data refresh events from all data producers. The central event bus forwards the events to consumer accounts. The consumer accounts filter the events consumers are interested in from data producers for their data processing needs.
Orchestration design
Stifel designed and implemented an event-based data pipeline orchestration system that triggers data pipelines when specific events occur. This system processes data immediately after receiving all required dependency events, enabling efficient workflow management.
The following diagram describes the logical architecture of the domain data pipeline orchestration framework.
The orchestration framework includes the components described in the following list. The data dependencies and data pipeline state management metadata are hosted in an Aurora PostgreSQL database.
Data refresh processor: Receives data refresh events from central mesh and local data domain and evaluates if the domain data products data dependencies are met
Data product dependency processor: Retrieves metadata for the product, kicks off a corresponding data domain AWS Glue job, and updates metadata with the job information
Data pipeline state change processor: Monitors the domain data jobs and takes actions based on the job’s final status (SUCCEED or FAILED) and then creates incident tickets for failed jobs
Conclusion
Stifel has improved its data management and reduced data silos by adopting a data product approach. This strategy has positioned Stifel to become a data-driven, customer-centric organization. The company combines federated platform practices with AWS and open standards. As a result, Stifel is achieving its decentralization objectives through a scalable data platform. This platform empowers domain teams to make informed decisions, drive innovation, and maintain a competitive edge. Here are the some of the advantages Stifel got from an event-driven domain architecture (EDDA):
Business agility: Rapid market response, new business capability integration, scalable domains, quicker feature deployment, and flexible process modification
Customer experience: Real-time processing, responsive interactions, personalized services, consistent omnichannel presence, and enhanced service availability
Operational efficiency: Reduced system coupling, optimal resource use, scalable systems, lower maintenance overhead, and efficient data processing
Cost benefits: Lower development costs, reduced infrastructure expenses, decreased maintenance costs, efficient resource usage, and a better ROI on technology investments
In this post, we demonstrated how Stifel is building a modern data platform by recognizing the critical importance of data in today’s financial landscape. This strategic approach not only enhances operational efficiency but also positions Stifel at the forefront of technological innovation in the financial services industry. To learn more and get started, see the following resources:
Amit Maindola is a Senior Data Architect focused on data engineering, analytics, and AI/ML at Amazon Web Services. He helps customers in their digital transformation journey and enables them to build highly scalable, robust, and secure cloud-based analytical solutions on AWS to gain timely insights and make critical business decisions.
Srinivas Kandi is a Senior Architect at Stifel focusing on delivering the next generation of cloud data platform on AWS. Prior to joining Stifel, Srini was a delivery specialist in cloud data analytics at AWS helping several customers in their transformational journey into AWS cloud. In his free time, Srini likes to explore cooking, travel and learn new trends and innovations in AI and cloud computing.
Hossein Johari is a seasoned data and analytics leader with over 25 years of experience architecting enterprise-scale platforms. As Lead and Senior Architect at Stifel Financial Corp. in St. Louis, Missouri, he spearheads initiatives in Data Platforms and Strategic Solutions, driving the design and implementation of innovative frameworks that support enterprise-wide analytics, strategic decision-making, and digital transformation. Known for aligning technical vision with business objectives, he works closely with cross-functional teams to deliver scalable, forward-looking solutions that advance organizational agility and performance.
Ahmad Rawashdeh is a Senior Architect at Stifel Financial. He supports Stifel and its clients in designing, implementing, and building scalable and reliable data architectures on Amazon Web Services (AWS), with a strong focus on data lake strategies, database services, and efficient data ingestion and transformation pipelines.
Lei Meng is a data architect at Stifel. His focus is working in designing and implementing scalable and secure data solutions on the AWS and helping Stifel’s cloud migration from on-premises systems.
Amazon Web Services (AWS) has been recognized as a Leader in The Forrester Wave: Serverless Development Platforms, Q2 2025, achieving the highest ranking in both the Current Offering and Strategy categories.
The Forrester Wave evaluation provides business leaders with rigorous, fact-based analysis for technology purchasing decisions. Through transparent criteria spanning current offering, strategy, and customer feedback, Forrester evaluates vendors to identify Leaders, Strong Performers, and Contenders. The AWS serverless portfolio unifies traditional and AI-driven development, enabling teams to build intelligent, adaptive systems with minimal infrastructure and code overhead. The evaluation analyzed across key services, including AWS Lambda for serverless compute, AWS Step Functions and Amazon EventBridge for application integration, and AWS Fargate with Amazon Elastic Container Service (Amazon ECS) for serverless containers.
Serverless beyond function-as-a-service
The serverless operating model has evolved beyond function-as-a-service approaches. It has become a comprehensive cloud-based software development model that abstracts away underlying cloud infrastructure, complex server configurations, runtime characteristics, and deployment patterns from the development process. Forrester defines key characteristics of serverless development platforms as supporting the deployment of arbitrary business logic, decoupled state from the underlying compute, autonomous scale by demand (often back to zero), flexible consumption-based billing, abstraction of the underlying cloud infrastructure, and event-driven communication.
According to the Forrester report, “AWS provides a mature foundation for event-driven application development with extensive integrations across the AWS ecosystem. AWS continues to evolve its serverless portfolio for market demands including the growing influence of AI workloads. AWS’s platform completeness and integration depth are notable, making it well-suited for organizations seeking to build production-grade event-driven applications at scale with granularity and control.”
AWS capabilities recognized in the report
AWS’s recognition as a Leader in this report underscores, for us, our commitment to providing best-in-class innovation and developer experiences in serverless application development. Findings from AWS’s vendor profile in the report include:
Strategy – AWS has a clear and cohesive vision that aligns serverless capabilities across its expansive cloud portfolio. Its innovation strategy is tightly coupled with customer feedback and reinforced through sustained R&D investment.
Capabilities – AWS offers strong capabilities across developer experiences, tools, and service integrations. Developers benefit from mature software development kits (SDKs), command line interface (CLI) tools, and infrastructure as code (IaC) options. Its APIs and event-driven integrations are among the best, enabling complex, scalable architectures and workflows.
Evolving serverless developer experience on AWS
AWS has made significant investments to streamline the developer onboarding experience through comprehensive resources and tools. As generative AI infuses every step of software development and transforms the technology landscape, organizations must adapt quickly to maintain their competitive edge. Many are building distributed architectures that use specific large language models (LLMs) based on unique requirements, and the serverless operating model is ideal for these AI-powered applications. Serverless enables organizations to start small and scale seamlessly while handling distributed, event-driven workflows securely at scale.
The newly launched AWS Serverless Model Context Protocol (MCP) server provides AI-powered, contextual guidance throughout the serverless development lifecycle, so developers can receive real-time assistance with service selection, best practices, and implementation patterns while building applications with Lambda. The developer-first approach also includes the Amazon Q Developer plugin for AI-assisted development (including code generation, debugging, and architectural guidance), enhanced AWS SAM CLI capabilities for improved local testing and debugging, the integration with Serverless Land for direct blueprint access on the Lambda console, extensive documentation with practical examples, interactive tutorials, and integration with familiar development environments. AWS has also enhanced the getting started experience through simplified deployment workflows, IaC templates, and automated best practices enforcement. Furthermore, the broad ecosystem of AWS partners, developer advocates, and community contributors provides additional support through workshops, sample applications, and reference architectures. These comprehensive improvements demonstrate our commitment to accelerating serverless adoption by making development more intuitive, efficient, and accessible for teams at any stage of their cloud journey.
Conclusion
AWS has been recognized as a Leader in the Forrester Wave: Serverless Development Platforms, Q2 2025, receiving top scores in Current Offering and Strategy categories, which, in our opinion, underscores our commitment to innovation and excellence in serverless computing. As the serverless landscape continues to evolve, AWS remains at the forefront, providing a comprehensive suite of services that enable developers to build scalable, efficient, and intelligent applications.As we look to the future, AWS will continue to invest in serverless technologies, pushing the boundaries of what’s possible in cloud computing. Whether you’re building AI-powered applications, modernizing legacy systems, or creating entirely new digital experiences, AWS serverless offerings provide the agility, scalability, and innovation you need to stay ahead in a rapidly evolving digital landscape.
Read the full report to learn why Forrester positioned AWS as a Leader in the Forrester Wave: Serverless Development Platforms, Q2 2025.
Forrester does not endorse any company, product, brand, or service included in its research publications and does not advise any person to select the products or services of any company or brand based on the ratings included in such publications. Information is based on the best available resources. Opinions reflect judgment at the time and are subject to change. For more information, read about Forrester’s objectivity here .
When I began my career in security, most people accepted as fact that protecting systems came at the expense of productivity. That didn’t have to be true then, and it’s definitely not true now. The cloud, and specifically the AWS Cloud, is a big reason why. But as technology evolves and systems become more complex, operating at scale demands a fresh approach to security. We take our customers’ security seriously, and that means building guardrails that give organizations the confidence to innovate boldly and scale rapidly.
In my new role as AWS CISO, I see this playing out daily. As I meet with customers, their excitement about technologies like generative AI comes hand in hand with questions about securing complex environments and managing new types of risk. They’re excited about innovation, but they need confidence that their security foundations can keep pace with their ambitions. They want to move fast without compromising security.
Today at re:Inforce, I shared how AWS is working backward from these needs to fundamentally transform how security scales in the cloud. It all starts with a security foundation built on four key pillars: identity and access management, data and network security, monitoring and incident response, and the continuous work of migration, modernization, and patching. Organizations with mature security models across these pillars are the ones moving fastest. Across each of these areas, we’re focused on delivering security capabilities that help customers adopt new technologies and experiment with confidence.
Scaling identity for the cloud
As our customers rapidly scale their cloud operations, they’ve told us that managing identity and access across complex environments becomes increasingly challenging. They need solutions that can grow with their business while maintaining strong security. Identity and access management underpins every aspect of cloud security, and success in this area requires both rigorous authentication controls and comprehensive visibility into access permissions.
I was excited to announce new internal access findings for AWS IAM Access Analyzer today. This capability transforms how organizations manage access to sensitive data at scale, addressing the complexities our customers face as they grow. Using automated reasoning technology, it analyzes complex permission layers across diverse policy types, giving security teams comprehensive visibility into who within their organizations has access to what resources. With daily monitoring and notifications of new access granted, we’re helping teams implement least-privilege access with confidence in even the most complex environments. This provides our customers visibility to strengthen access controls on their critical resources while maintaining the agility their business demands as they scale in the cloud.
Empowering transformation through data and network security
Our customers are eager to transform their businesses, but they need confidence that their security can keep pace with rapid innovation. This is especially true when it comes to protecting their networks and data at scale. During the keynote, Noopur Davis, CISO of Comcast, shared how her organization protects their vast network and customer data while enabling rapid innovation. With millions of customers relying on their services, Comcast’s approach resonated with me: security shouldn’t just defend, it should enable transformation.
We’re delivering on this vision with new capabilities that simplify security at scale. Today, I announced that AWS Certificate Manager now allows you to export ACM-issued public certificates and their private keys for use inside or outside of AWS, giving you automated certificate management with the flexibility to help secure your workloads. We’re also expanding AWS Shield with enhanced network and application protection that performs a network security analysis to identify configuration issues and provides remediation recommendations. You can even use AWS generative AI powered assistant Amazon Q Developer to gain actionable insights using simple natural language. These innovations help teams protect their data and stay ahead of evolving threats even as their environments grow more complex.
Elevating threat detection and response
Our customers have shared their challenges in keeping pace with the evolving threat landscape, especially as they scale their cloud operations. While traditional automation helps manage growing complexity, AI represents an even more powerful opportunity to transform security operations. When implemented thoughtfully, AI dramatically improves our ability to spot complex attack patterns, reduce false positives, and automate responses at massive scale.
Today at re:Inforce, I announced two key security innovations: expanded capabilities in Amazon GuardDuty Extended Threat Detection and enhanced AWS Security Hub that directly address these needs. Together, these services help simplify security at scale. GuardDuty uses AWS-trained AI and machine learning (AI/ML) models to detect sophisticated multi-stage threats and provide actionable insights, while Security Hub prioritizes critical security issues by automatically analyzing and correlating security signals into clear, prioritized actions. This approach gives teams the confidence to scale their operations, knowing they can detect and respond to security risks efficiently across their entire AWS environment.
Accelerating the journey to better security
While advanced capabilities like AI and automation help strengthen security operations, the foundation matters most. Moving to the cloud represents a transformative opportunity to build on a fundamentally stronger security foundation than most organizations can ever hope to achieve with on-premises environments. When migrating to AWS, you reduce the need to manage physical infrastructure security while gaining access to built-in protections that are continuously updated and maintained.
Successful cloud adoption means going beyond simple lift-and-shift. Modernization is key to realizing these benefits. By moving solutions further up the stack to use managed services like AWS Lambda, Amazon Simple Storage Service (Amazon S3), or AWS Key Management Service (AWS KMS), you benefit from security controls that are built in rather than bolted on. These services are continuously patched and maintained by AWS, freeing your teams to focus on innovating for your customers. After all, the fastest path to better security is the one where core protections are already built in.
Partnering for security success
Security transformation isn’t a journey organizations need to take alone. Throughout my career, I’ve seen how the right partnerships can accelerate success, bringing fresh perspectives and deep expertise to complex challenges. Our security partners help customers across the four pillars we discussed today, from implementing identity solutions to modernizing security operations. They understand both the technical complexities and the business realities of scaling security in the cloud, often bringing valuable industry-specific experience that helps organizations move faster with confidence.
Looking ahead
As you scale your operations in the cloud, our goal is to give you the confidence to move quickly while maintaining strong security controls. When security scales naturally with your business, teams can focus on building what’s next instead of managing infrastructure.
To dive deeper into how AWS designs, builds, and operates security at unprecedented scale, I encourage you to join our Innovation Talks at re:Inforce. These hour-long sessions explore the key pillars of modern cloud security: secure foundations, resilient architectures, AI-powered innovations, and large-scale threat intelligence.
As I step into my role as AWS CISO, I’m energized by the opportunity ahead. For nearly 20 years, AWS has maintained a unique culture of security that enables us to innovate rapidly while shipping securely. As we navigate the landscape of generative AI and rapid technological change, earning your trust means not just keeping pace with innovation, but helping to make it even more successful. I couldn’t be more excited to carry this mission forward.
If you have feedback about this post, submit comments in the Comments section below.
At AWS, security is the top priority, and today we’re excited to share work we’ve been doing towards our goal to make AWS the safest place to run any workload. In earlier posts on this blog, we shared details of our internal active defense systems, like MadPot (global honeypots), Mithra (domain graph neural network), and Sonaris (network mitigations). We’re still inventing new ways to improve the effectiveness of threat intelligence and automated response to detect and help prevent attacks. Today we’ll share advancements in active defense related to malware, software vulnerabilities, and AWS resource misconfigurations. Like the other posts we linked to, these are constantly improving capabilities that our customers get just for being on the AWS network. We’ll discuss these topics in more depth at re:inforce 2025 during Innovation Talk SEC302.
Stopping malware from spreading
Financially motivated threat actors try to gain access to a wide array of networked assets. The more resources they control, the more places they can hide, and the longer they can profit from their abusive operations. As such, threat actor malware often contains modules to scan for new targets, replicate binaries over the network, and then repeat. If left unchecked, such rapidly spreading behavior can lead to network congestion, service availability loss, and data destruction. We want to help prevent this behavior to the greatest degree possible.
One effective strategy we employ is identifying the threat actor’s key infrastructure where malware is centrally controlled. We use a variety of techniques to identify, verify, track, and disrupt threat infrastructure. Using network traffic logs, honeypot interactions, and malware samples from an array of sensor positions, we mitigate botnets, abusive proxies, and peer-to-peer malware. Over the past 12 months, AWS helped prevent over 4 million malware infection attempts across 315 thousand distinct Amazon Elastic Compute Cloud (Amazon EC2) instances. By protecting workloads from these malware infections, we not only protect our network and our customers, but also the broader internet from further malware expansion.
Advancements in threat hunting and mitigating software vulnerabilities
At Amazon, we’re proud to support software vulnerability research with programs for bug bounty, vulnerability disclosure, and open source contribution. We’ve also become a more active participant in the CVE process by becoming a CVE Numbering Authority (CNA) for the software and services provided by Amazon. Thanks to the public CVE database, we see vulnerability research accelerating as reported CVEs have grown by 21 percent year-over-year since 2013, with over 40 thousand CVEs published in 2024. This virtuous cycle of finding and resolving vulnerabilities improves cyber security over time, but AWS sees threat actors searching for unresolved vulnerabilities to gain unauthorized access to resources.
We’ve expanded MadPot and Sonaris to identify and stop a broader range of malicious vulnerability scanning and exploitation activity, protecting every AWS customer from vulnerability exposure. We’ve added hundreds of new detections and MadPot service emulations to identify real attacks. As we’ve expanded our visibility, we’ve continued blocking hundreds of millions of CVE exploit attempts daily across the AWS network.
As we’ve made these active defense systems better at stopping CVE exploit attacks, the total number of attacks has gone down by over 55 percent in the last 12 months, as shown in Figure 1. There are many factors outside our control in this observation, but we’re happy to see fewer CVE exploit attacks. This trend coincides with the detection, regionalization, latency, and guardrail improvements we’ve made in 2025. No system can block everything, so fewer exploit attempts mean less risk across a wide range of workloads.
Figure 1: Chart showing the decrease in global malicious vulnerability exploit attempts
This work to identify known exploits in the wild directly benefits users of vulnerability intelligence in Amazon Inspector, which provides an Amazon Inspector score for customers to prioritize where to spend security hardening resources. This includes the most recent date of observed exploitation attempts, the MITRE ATT&CK techniques associated with the exploit activity, and the industries targeted.
Protecting architectures built on AWS
AWS actively defends compute and network resources for our customers; we also defend the distinct AWS-native resources that customers rely on. AWS access key credentials are a critical resource that allow access to customer accounts. The AWS Identity and Access Management best practices share proven techniques for customers to keep their credentials from being abused. Through active defense, we do even more to help customers who haven’t yet adopted these best practices.
Each day, AWS helps prevent an average of 167 million malicious scanning connections seeking unintentionally exposed AWS access key pairs. In case access keys are discovered through other means, we’ve expanded our protection of customer-managed IAM credentials. When our threat intelligence analytics show that a customer-managed credential is known by a threat actor, we put mitigations in place to restrict access to highly privileged operations. We also send customized notifications to help customers identify how the credential was exposed. These efforts are paying off for our customers every day; the following response is a good example of what we hear regularly:
This is a key that we already rotated a few weeks ago based on another alarm from you. It turned out that the new rotated key happened to be in your second alarm to us. So it meant that the app that the key was linked to was still leaking it.
So on Monday we sat down with the dev team, found where the app was leaking some secrets from, we patched it, I rotated all the exposed secrets (it was more than the IAM key) and we plugged in the extra security in the app.
So thanks again for those alerts, they are very precious. – AWS Customer
In a specific case of threat activity in November and December of 2024, customers reported ransomware activity against their objects in Amazon Simple Storage Service (Amazon S3) storage. We saw that these ransom threats were highly correlated with exposed customer-managed IAM keys. We applied quarantines to the exposed keys, taking care to make sure that normal customer operations could continue safely. We re-sent our proactive notifications to customers about keys that were likely exposed, because the risk of an attack was elevated. During this period, we worked together with customers to deactivate over 30 thousand exposed credentials. Since this threat activity began, AWS has helped prevent over 943 million malicious attempts to encrypt customer Amazon S3 objects.
These credential exposure detections flow into Amazon GuardDuty Extended Threat Detection, simplifying threat detection and response operations for modern cloud environments.
Better together
The approach AWS takes to active defense shows how security can be improved by layering protections across the infrastructure stack and using threat intelligence to drive risk reduction. By building active defense into our services at no extra cost, AWS helps our customers stay protected from a wide range of threats.
While we continue to constantly improve our protections for our customers, some of our work is by nature probabilistic, because we never see inside customer workloads. We don’t apply active defense in situations where the detection is ambiguous, because that might impact our customers’ production systems. To stay secure, customers should never let down their own defenses. AWS security services like AWS Identity and Access Management (IAM), AWS Shield Advanced, AWS WAF, AWS Network Firewall, Amazon GuardDuty, and Amazon Inspector provide prevention, detection, and response that customers can configure for their unique needs. The good news is that by working together, we’re making the internet safer for everyone.
If you have feedback about this post, submit comments in the Comments section below.
Today, Amazon Web Service (AWS) introduces the Security Champion Knowledge Path on AWS Skill Builder, featuring training and a digital badge. The Security Champion Knowledge path is a comprehensive educational framework designed to empower developers and software engineers with essential AWS cloud security knowledge and best practices. The structured learning path enables development teams to accelerate their delivery while maintaining robust security standards in cloud environments, addressing customers’ need for a structured curriculum to develop and validate security expertise across their organizations.
A new era of security education
The AWS Security Champion Knowledge Path complements the existing AWS security training offerings, providing a structured, self-paced journey to security expertise. Hart Rossman, Vice President of Global Services Security at AWS, emphasizes the program’s significance: “Security in the cloud isn’t a destination; it’s an ongoing journey. The AWS Security Champion Knowledge Path equips our customers with the tools and knowledge to navigate this journey confidently, fostering a culture where security is woven into every aspect of cloud operations.”
Designed for a diverse audience including software developers, solutions architects, technical leaders, and cloud practitioners, the training plan covers a wide range of topics that are critical for a strong security posture in the cloud. This AWS security learning journey begins with essential fundamentals and progressively builds toward advanced concepts across a well-structured curriculum. Starting with AWS Security Fundamentals and the AWS Shared Responsibility Model, learners establish core principles before diving into AWS Identity and Access Management (IAM), including detailed troubleshooting scenarios. The curriculum advances to critical security elements such as encryption and comprehensive threat modeling through the AWS Builders Workshop. Security governance and auditing form the next tier, followed by practical implementations of monitoring, alerting, and network infrastructure best practices. The learning path then covers specialized areas including web-facing workload protection, network control, and incident response procedures. The knowledge path culminates with deep dives into container security and core security concepts through AWS SimuLearn, providing hands-on experience with real-world scenarios. This carefully orchestrated progression helps facilitate a thorough understanding of AWS security principles while maintaining a practical, implementation-focused approach.
What is a Security Champion?
A Security Champion is a bridge between security teams and development teams, promoting security best practices and making sure that security is embedded into every stage of the development lifecycle. However, Security Champion isn’t just a role—it’s a mindset. In today’s distributed and agile cloud environments, having Security Champions across different teams provides a competitive advantage for releasing products quickly and securely.
This distributed ownership of security brings numerous benefits: faster development cycles because teams can address security requirements proactively, reduced security incidents through early detection, and improved collaboration between security and development teams. Most importantly, it creates a culture of security where every team member understands their role in protecting the organization’s assets and data.
By becoming a Security Champion, you’ll gain valuable expertise, earn recognized credentials, and develop leadership skills that can accelerate your career growth. Most importantly, you’ll be empowered to make meaningful contributions to your organization’s security posture by promoting best practices, identifying potential vulnerabilities early in the development cycle, and fostering collaboration between teams—ultimately helping your organization deliver products that are both innovative and secure.
How can I become an AWS Security Champion?
Security enthusiasts can enroll into the AWS Security Champion Knowledge Badge Readiness Path on AWS Skill Builder and complete the assessment successfully to earn the AWS Security Champion digital badge available on Credly.
AWS Security Champion training is a self-paced, hands-on, and interactive approach to upskilling on security concepts. As a participant, you’re introduced to security best practices, performing basic audits, planning for governance at scale, incident response concepts and more. You can engage with real-world scenarios through hands-on labs, interactive game-based learning, gain access to AWS sandbox environments, and conduct practical security assessments. This applied learning helps make sure that knowledge isn’t just acquired, but truly internalized and ready for immediate application.
“The AWS Security Champion Knowledge Path represents a significant milestone in democratizing security expertise. We’ve designed this program to transform how organizations approach security training, making it accessible, practical, and immediately applicable. This isn’t just about learning security concepts—it’s about creating a culture where security becomes second nature to every team member.” – Jenni Troutman, Training and Certification Director at AWS
Recognition and community
Upon successfully completing the assessment in this training path, participants earn the prestigious AWS Security Champion knowledge badge in Credly to showcase their accomplishment, such as on LinkedIn, and join a growing community of security professionals. This recognition not only validates individual expertise but also signals an organization’s commitment to security excellence, and helps organizations identify qualified security champions within their team.
Getting started
To begin your journey to becoming an AWS Security Champion, log in or create an account with AWS Skill Builder and enroll in the Security Champion Knowledge Badge Readiness Path. The training plan is available through flexible pricing options, including individual subscriptions at $29 per month and team subscriptions at $449 per month with enterprise volume pricing available.
Rossman concludes, “The AWS Security Champion Knowledge Path represents a paradigm shift in how organizations approach security education. It’s about creating a shared language of security across teams, enabling faster, more secure development cycles, and ultimately, delivering better outcomes for our customers.”
Ready to elevate your organization’s security capabilities? Visit AWS Skill Builder to enroll and start your journey towards becoming an AWS Security Champion. For enterprise inquiries, reach out to your AWS account team.
Stay tuned to the AWS Security Blog for more updates on AWS Security services, features, and best practices. Together, we’re building a more secure cloud for all.
If you have feedback about this post, submit comments in the Comments section below.
Customers often tell me that they want a simpler path to meet the compliance and industry regulatory mandates they have in their geographic regions. In our deep engagements with partners and customers, we have learned that one of the greatest challenges for customers is the translation of security and compliance requirements into distinct technical controls. At Amazon Web Services (AWS), security is our top priority, and we understand that protecting your data in a world with changing regulations, technology, and risks takes teamwork. As we’ve said, security is foundational to sovereignty.
AWS helps organizations to develop and evolve security, identity, and compliance into key business enablers; that’s why we’re committed to working with national cyber authorities and regulators to help define and establish how their compliance standards can be translated into security best practices in the cloud. We’re responding to customer requests to create locally tailored approaches aligned to their own regional standards and guidance as established by in-region authorities.
Architectural best practice, locally tailored
Since its launch in 2022, Landing Zone Accelerator on AWS has been instrumental in helping thousands of customers deploy cloud foundations that align with multiple global compliance frameworks and AWS best practices, including the Baseline Informatiebeveiliging Overheid (BIO) in the Netherlands, and the Esquema Nacional de Seguridad (ENS) in Spain. AWS is committed to expanding our regional implementations to help customers meet specific national and regional standards and digital sovereignty goals.
In March, I was proud to share the news of the cooperation agreement between the Federal Office for Information Security (BSI) and AWS, where AWS committed to help advance digital sovereignty and cybersecurity best practices and standards in Germany and across the European Union. With that in mind, I’m excited to share that our next regional implementation of Landing Zone Accelerator on AWS will support customers with workloads in Germany. The C5-ready Landing Zone Accelerator is designed to help customers meet their Cloud Computing Compliance Criteria Catalogue (C5) compliance objectives in the cloud. This will be available to our customers in Q3-2025, and at launch, our regional implementations will also be available in AWS European Sovereign Cloud.
For many customers in Germany, adherence to C5 is a requirement, and this is evidenced through a compliance assessment by an authorized assessor. Preparing for this assessment is critical for a successful outcome and is why AWS has partnered with AWS Global Security & Compliance (GSCA) Partner Schellman to provide the assessor insight as to how the C5-ready Landing Zone Accelerator can accelerate and simplify the path to C5 adoption for AWS customers.
AWS Partner Schellman: Proven Track Record in C5 Assessments
As one of the few firms with deep expertise and experience in C5 assessments, Schellman has completed several dozen evaluations across a wide range of clients—from agile startups to global enterprises. This diverse portfolio underscores Schellman’s capabilities, deep technical expertise, and unwavering commitment to security assurance.
“Our team has seen firsthand how the C5 standard fosters transparency and builds trust in cloud services. We’re proud to support our clients not just in understanding C5, but in strategically leveraging it to improve security and competitiveness on a global scale.” Jeff Schiess, Managing Director, Schellman
Lowering the Barrier to Entry – Schellman recognizes that achieving C5 compliance can sometimes be intimidating, particularly for organizations new to the framework. To that end, Schellman has performed an assessment against the foundational infrastructure provided by LZA on AWS, designed to simplify the C5 journey. The LZA provides preconfigured infrastructure templates and security baselines that significantly reduce the complexity of establishing C5-compliant cloud environments.
“With the Landing Zone Accelerator, organizations can build on a C5-ready foundation right from the start. It’s a practical, scalable solution for companies that might otherwise find the C5 standard overwhelming.” Kristen Wilbur, Principal, Schellman
Sovereign by design
Landing Zone Accelerator on AWS automatically implements hundreds of security capabilities that map to control requirements across geographic compliance frameworks. This saves customers hundreds of hours in planning and implementing secure networking and account configurations by providing them with a foundation based on the AWS Well-Architected Security Pillar and AWS security best practices. Meeting compliance requirements, having verifiable access controls and data transfer restrictions, independence and choice over the technology stack, and surviving large-scale disruptions are some of the key capabilities that customers require of a sovereign-by-design workload. However, for many customers, translating regulatory requirements into a set of discrete technical controls and applying them consistently across one or more AWS accounts and AWS Regions can be time-intensive and challenging.
We provide customers and partners with detailed guidance on how to configure Landing Zone Accelerator on AWS in accordance with their local security and compliance requirements, including digital sovereignty requirements. This includes control mapping to local regulations or policies that shows customers how controls implemented in a landing zone are mapped to the specific requirements, calling out where customers are required to do more to meet these as part of our shared responsibility model—this includes organizational policies and procedures where customers must implement additional controls within their application or workload to meet local requirements.
Control over the location of your data
Landing Zone Accelerator on AWS provides customers with a choice of configurable preventative, detective, and proactive controls to help customers meet their data residency, security, and compliance objectives, whether you’re a public sector customer wanting to keep data in a single Region or navigating the complex needs of multi-national organizations with operations subject to differing digital sovereignty requirements.
Verifiable control over data access
Landing Zone Accelerator on AWS goes beyond just provisioning a secure, multi-account environment. It establishes a well-structured, multi-account architecture using AWS Organizations. This logically isolates workloads, management functions, and security controls into dedicated organizational units (OUs). This not only enhances security and operational efficiency, but also helps customers to enforce consistent data residency, access management, and compliance policies across their entire cloud footprint. These powerful guardrails empower customers to quickly harness the innovative potential of cloud technologies, whilst delivering business value from an established security and compliance baseline.
By providing this automated approach, AWS empowers organizations to rapidly deploy cloud environments tailored to their specific local requirements in days instead of weeks; with robust security, compliance, and operational guardrails in place from the outset. Landing Zone Accelerator on AWS is designed to simplify the path to cloud adoption and compliance for organizations, particularly those in regulated industries or with sovereignty requirements. This approach marks a shift from the previous heavy lift required for organizations to migrate workloads to the cloud while meeting their needs.
Partners at the core
There is a lot of complexity involved with navigating the evolving digital sovereignty landscape—but you don’t have to do it alone. Our AWS Digital Sovereignty Competency connects customers with trusted partners with demonstrated expertise to advise and architect for their customers’ digital sovereignty needs while taking advantage of the full potential of the AWS Cloud. As part of the competency, AWS is supporting partners to navigate customer challenges across four pillars: data residency, data protection, access control, and survivability.
Customers have told me about how challenging it can be to architect to address their sovereignty needs, often requiring manual iteration and longer time to value. Using Landing Zone Accelerator on AWS is one of the ways AWS and AWS Partners can work together to address customers’ sovereignty needs with a repeatable approach that helps our customers and partners move faster. I’m excited by how regional implementations of Landing Zone Accelerator on AWS is helping AWS Sovereignty Partners, such as Atos and SVA, to move faster without compromise.
“Compliance with regulations like C5 is essential for customers in the public sector and regulated industries, who prioritize digital sovereignty, and this is central to our Cloud for Clinics initiative with AWS in the German Healthcare market. The availability of the C5 LZA significantly reduces the technical complexity, giving us a common technical platform to build on reducing time to market. Atos is driving the operational rollout and expanding the scope of compliance mappings to further streamline customer compliance. At the same time, we are incorporating essential managed services like SOC/SIEM which we believe will make compliant cloud adoption easier to drive innovation by the Public Sector, Healthcare institutions or customers in regulated industries like Financial Services and Utilities.” Boris Hecker, Managing Director, ATOS Germany
“Compliance with BSI C5 criteria for customers from the public sector and regulated industries is a basic requirement for the use of public cloud services. Implementing the regulations is often complex, time-consuming and resource-intensive. For this reason, customers are looking for solutions that they can tailor to the specific requirements of their industry; while ensuring they meet compliance standards. SVA supports customers in maintaining the balance between innovation and compliance with customized, C5-certified, managed services. We rely on solutions such as the Landing Zone Accelerator on AWS to reconcile the use of market-leading public cloud infrastructure with regulatory requirements.” Patrick Glawe, Hyperscaler Lead at SVA
Email communication remains a critical component of business operations and customer engagement. As the digital landscape evolves, major mailbox providers continually update their policies to enhance security and user experience. This blog will explore the changes implemented by Microsoft for bulk senders trying to reach Outlook.com (supporting Hotmail.com, live.com consumer domain addresses). This follows the Google & Yahoo! bulk sender requirements changes in February of 2024. Microsoft is implementing the enforcement of sender requirements for bulk email senders, particularly those sending over 5,000 messages daily, starting May 5, 2025. These requirements focus on improving email authentication and trust. This will ensure Outlook and Hotmail recipients are receiving messages that are authenticated and from who they claim to be from. These measures will help reduce spoofing, phishing, and spam, and safeguarding individuals and businesses relying on email.
This blog will discuss what these changes mean for you, and how Amazon Simple Email Service (Amazon SES) can help you maintain compliance and optimize your email sending practices.
Background
In February 2024, Google and Yahoo implemented new requirements for bulk email senders, building upon industry efforts to combat spam and improve email deliverability. These changes aligned with Google’s 2024 bulk sender requirements initiative, signaling a unified approach among major mailbox providers to enhance the privacy and compliance in email.
What does this mean for customers and email senders?
Requirement for From and Reply-to addresses to be deliverable
Why These Changes Matter?
These new requirements serve several crucial purposes:
Enhances trust in your sending domain: Validates that the sender is who they are claiming to be. Enhances trust by delivering messages that are authenticated and aligned with the bulk sender requirements.
Improved Deliverability: Ensuring legitimate emails reach the recipients who have subscribed to sender’s messages.
Industry Standardization: Aligning sender requirements across major email providers
Best Practices for Compliance
To adhere to these new requirements and optimize your email sending practices, consider the following best practices:
1. Implement Strong Authentication
Configure SPF: SPF (Sender Policy Framework) is an email authentication standard that’s designed to prevent email spoofing. Domain owners use SPF to tell email providers which servers are allowed to send email from their domains. Follow setup instructions to authenticate your email with SPF. Must pass SPF for sending domain.
Configure “custom MAIL FROM“, which is how senders can ensure that the SPF-authenticated domain is aligned with the From header domain’s DMARC policy.
Enable DKIM signing: DomainKeys Identified Mail (DKIM) is an email security standard. It is designed to ensure that an email that claims to have come from a specific domain, was indeed authorized by the owner of that domain. It uses public-key cryptography to sign an email with a private key. Recipient servers use a public key, published to a domain’s DNS to verify that parts of the email have not been modified during the transit. Follow these set up instructions to authenticate email with DKIM in SES. Must pass to validate email integrity and authenticity.
Verify your domain with Easy DKIM. If currently using email identities, you have to move to domain
If you utilize email identities only, you will default all authentication to amazonses.com. That will not align with your friendly from address which will not satisfy the bulk sender requirements. This means that when you send email to mailbox providers, your messages will be rejected because you do not have proper authentication on your emails. To satisfy the bulk sender requirements, you must use domain verified identities which ensure that you have ownership of or permission to use the sending domain. That will allow SES to sign the outgoing emails with a DKIM signature that aligns with the friendly from domain.
Set up DMARC with an appropriate policy: Domain-based Message Authentication, Reporting and Conformance (DMARC) is an email authentication protocol that uses SPF and DKIM to detect email spoofing and phishing. To comply with DMARC, messages must be authenticated through either SPF or DKIM. Ideally, when both are used with DMARC, you’ll be ensuring the highest level of protection possible for your email sending.
Value of the TXT record contains the DMARC policy that applies to your domain.
In this example, the policy tells email providers to do the following:
At least p=none should be implemented.
2. Optimize Email Content
Clearly identify yourself as the sender: Use a recognizable “From” name and email address that accurately represents your brand or organization. For example, use “[email protected]” instead of a generic or misleading address.
Implement user friendly unsubscribe mechanisms: Include a visible, easy-to-use unsubscribe link in every email, typically in the header. Ensure the unsubscribe process is simple and honors requests promptly, ideally within 24-48 hours. Visit this guide on how Amazon SES helps you do that.
Subject line aligns with content: Avoid deceptive subject lines that don’t match the email content.
Clearly identify commercial content: If your email is promotional, make it obvious. Use clear language in the subject line and body that indicates the nature of the email, such as “Special Offer” or “Newsletter.”
Include a valid physical address: Add your company’s physical mailing address in the email footer. This is not only a legal requirement in many jurisdictions but builds trust with recipients.
Verify URLS in the emails: Verify that links in the emails you send work and are not misleading to the reader/subscriber. Be transparent with URLs/links in the email content.
3. Monitor and Maintain
Monitor bounces: A bounce typically indicates why a message was not delivered. The SMTP response in the bounce message will have details on why the message was bounced. For example: if it is missing authentication records (fix: include authentication records for the domain – quick fix) versus an IP or domain reputation bounce reason (this maybe a longer term fix).
Track both hard bounces (permanent delivery failures) and soft bounces (temporary issues). High bounce rates can indicate list quality problems or delivery issues. Visit this blog to set up notifications for bounces & complaints. Virtual Deliverability Manager (VDM) is an Amazon SES feature that helps you enhance email deliverability. It helps increasing inbox deliverability and email conversions, by providing insights into your sending and delivery data. VDM advices on how to fix the issues that are negatively affecting your delivery success rate and reputation.
Track complaint rates: Regularly monitor the number of spam complaints your emails receive with a goal of keeping the complaint rate under 0.2%. Not all mailbox providers have complaint feedback loop data, so use aggregate data from the mailbox providers that do, such as Hotmail and Yahoo. Email providers that don’t provide complaint feedback loops, such as Gmail may have alternative dashboards or tools available like Google Postmaster tools.
Perform regular authentication checks: Periodically verify that your SPF, DKIM, and DMARC records are correctly set up and functioning. Alternative to manual DNS checks, Amazon SES has a feature in Virtual Deliverability Manager that performs authentication checks for your sending identities.
Maintain list hygiene: Regularly clean your email list by removing inactive subscribers, correcting typos in email addresses, and honoring unsubscribe requests. This helps improve deliverability and engagement rates.
How Amazon SES Helps
Amazon SES provides a robust set of features to help you meet these new requirements and optimize your email sending practices:
The new bulk sender requirements from Microsoft and Yahoo represent an important step towards a more secure and reliable email ecosystem. By leveraging Amazon SES’s powerful features and following industry best practices, you can maintain compliance, improve deliverability, and enhance the overall effectiveness of your email communications.
Amazon SES is committed to helping you navigate these changes and optimize your email sending practices. For the most up-to-date guidance and support, please consult SES’s documentation or contact Amazon SES support.
Coding agents powered by large language models have shown impressive capabilities in software engineering tasks, but evaluating their performance across diverse programming languages and real-world scenarios remains challenging. This led to a recent explosion in benchmark creation to assess the coding effectiveness of said systems in controlled environments. In particular, SWE-Bench which measures the performance of systems in the context of GitHub issues has spurred the development of capable coding agents resulting in over 50 leaderboard submissions, thereby becoming the de-facto standard for coding agent benchmarking. Despite its significant impact as a pioneering benchmark, SWE-Bench, and in particular its “verified” subset, also shows some limitations. It contains only Python repositories, the majority of tasks are bug fixes, and at over 45% of all tasks, the Django repository is significantly over-represented.
Today, Amazon introduces SWE-PolyBench, the first industry benchmark to evaluate AI coding agents’ ability to navigate and understand complex codebases, introducing rich metrics to advance AI performance in real-world scenarios. SWE-PolyBench contains over 2,000 curated issues in four languages. In addition, it contains a stratified subset of 500 issues (SWE-PolyBench500) for the purpose of rapid experimentation. SWE-PolyBench evaluates the performance of AI coding agents through a comprehensive set of metrics: pass rates across different programming languages and task complexity levels, along with precision and recall measurements for code/file context identification. These evaluation metrics can help the community address challenges in understanding how well AI coding agents can navigate through and comprehend complex codebases
Below, we describe the key features, characteristics, and the creation process of our dataset alongside the new evaluation metrics, and performance of open source agents from our experiments.
Extensive Dataset: 2110 instances from 21 repositories ranging from web frameworks to code editors and ML tools, on the same scale as SWE-Bench full with more repository.
Task Variety: Includes bug fixes, feature requests, and code refactoring.
Faster Experimentation: SWE-PolyBench500 is a stratified subset for efficient experimentation.
Leaderboard: A leaderboard with a rich set of metrics for transparent benchmarking.
Building a comprehensive dataset
The creation of SWE-PolyBench involved a data collection and filtering process designed to ensure the quality and relevance of the benchmark tasks. SWE-Bench, a benchmark for Python code generation, evaluates agents on real-world programming tasks by utilizing GitHub issues and their corresponding code and test modifications. We extended the SWE-Bench data acquisition pipeline to support 3 additional languages besides Python and used it to gather and process coding challenges from real-world repositories as shown in Figure 1.
Figure 1: Overview of the SWE-PolyBench data generation pipeline, illustrating the process of collecting, filtering, and validating coding tasks.
The data acquisition pipeline collects pull requests (PRs) that close issues from popular repositories across Java, JavaScript, TypeScript, and Python. These PRs undergo filtering and are set up in containerized environments for consistent test execution. The process categorizes tests as fail-to-pass (F2P) or pass-to-pass (P2P) based on their outcomes before and after patch application. Only PRs with at least one F2P test are included in the final dataset, ensuring that each task represents a meaningful coding challenge. This streamlined approach results in a dataset that closely mimics real-world coding scenarios, providing a robust foundation for evaluating AI coding assistants.
Dataset characteristics
When constructing SWE-PolyBench, we aimed to collect GitHub issues that represent diverse programming scenarios: issues involving modifications across multiple code files and spanning different task categories (such as bug fixes, feature requests, and refactoring). Tables 1 and 2 provide descriptive statistics on the composition and complexity of SWE-PolyBench full (PB) and SWE-PolyBench500 (PB500). To offer a point of reference, we compare these statistics with those of SWE-Bench (SWE) and SWE-Bench verified (SWEv). Tasks in SWE-PolyBench require on average more files to be modified and more nodes to be changed, which indicates that they have higher complexity and are closer to tasks in real-world projects. The distribution of tasks is also more diverse, in particular for SWE-PolyBench500.
New evaluation metrics
To comprehensively evaluate AI coding assistants, SWE-Polybench introduces multiple new metrics in addition to the pass rate. The pass rate is the proportion of tasks successfully solved as measured by the generated patch passing all relevant tests. It is the primary metric for assessing coding agent performance, but it doesn’t provide a complete picture of an agent’s capabilities. In particular, it doesn’t give much information on an agent’s ability to navigate and understand complex code repositories. SWE-PolyBench introduces a new set of metrics based on Concrete Syntax Tree (CST) node analysis and the established file-level localization metric:
File-level Localization: assesses the agent’s ability to identify the correct files that need to be modified within a repository. Let us assume that we would need to modify file.py to solve our problem. If our coding agent implements a change in any other file, it would receive a file retrieval score of 0.
CST Node-level Retrieval: evaluates the agent’s ability to identify specific code structures that require changes. It uses the Concrete Syntax Tree (CST) representation of the code to measure how accurately the agent can locate the exact functions or classes that need modification.
Figure 2: Illustration of CST node changes.
In Figure 2, we see a change in class node A materialized by a change in its initialization function on the left path starting from the file node. In contrast to the first change, the change in class B is considered a function node change as it doesn’t impact class construction.
Let us assume the change that would solve our problem is the change in the __init__ function. If our coding agent implements the change in my_func, it receives both a class and function node retrieval score of 0.
By combining pass rate assessment with both file-level and CST node-level retrieval metrics, SWE-PolyBench offers a detailed evaluation of AI coding assistants’ capabilities in real-world scenarios. This approach provides deeper insights into how well agents navigate and comprehend complex codebases, going beyond simple task completion to assess their understanding of code structure and organization.
Performance of open-source coding agents
Key Findings
Language Proficiency: Python is the strongest language for all agents, likely due to its prevalence in training data and existing benchmarks.
Complexity Challenges: Performance degrades as task complexity increases, particularly when modifications to 3 or more files are required.
Task Specialization: Different agents show strengths in various task categories (bug fixes, feature requests, refactoring).
Context Importance: The informativeness of problem statements impacts success rates across all agents (refer to Figure 5 of the appendix paper for details about this analysis).
Many existing open-source agents are designed primarily for Python. Adapting them to work for all four languages of SWE-PolyBench required adjusting test execution commands, modifying parsing mechanisms, and adapting containerization strategies for each language. We adapted and evaluated three open-source agents on SWE-PolyBench. The aforementioned adjustments are reflected by the added “-PB” suffix to the original agent names.
Figure 3: Performance of coding agents across programming languages and task complexities, highlighting strengths and areas for improvement.
Figure 3 provides a visual representation of agent performance across different dimensions:
Language Proficiency: The left side of the chart shows that all three agents perform best in Python, with significantly lower pass rates in other languages. This highlights the current bias towards Python in many coding agents and their underlying large language models.
Task Complexity: The right side of the chart illustrates how performance degrades as task complexity increases. Agents show higher pass rates for tasks involving single class or function changes, but struggle with tasks requiring modifications to multiple classes or functions and in instances where both class and function changes are required.
This comprehensive view of agent performance underscores the value of SWE-PolyBench in identifying specific strengths and weaknesses of different coding assistants, paving the way for targeted improvements in future iterations.
In addition to these insights, the evaluation revealed interesting patterns across different task categories as shown in Table 2. The performance data across bug fixes, feature requests, and refactoring tasks reveals varying strengths among AI coding assistants. The performance on bug fixing tasks is relatively consistent. There is more variability between different agents and between multiple runs of a given agent for feature request tasks and refactoring tasks.
Join the SWE-PolyBench community
SWE-PolyBench and its evaluation framework are publicly available. This open approach invites the global developer community to build upon this work and advance the field of AI-assisted software engineering. As coding agents continue to evolve, benchmarks like SWE-PolyBench play a crucial role in ensuring they can meet the diverse needs of real-world software development across multiple programming languages and task types.
Explore SWE-PolyBench today and contribute to the future of AI-powered software engineering!
Wicked6 Cyber Games 2025 brought hundreds of women together worldwide from March 28–30. This dynamic virtual competition, sponsored by Amazon Web Services (AWS), helped attendees tackle real-world cybersecurity challenges through e-sports experiences. With 72 hours of women talking about cybersecurity, 11 cybersecurity games, and an attack and defense tournament streamed live, the weekend-long event highlighted the value of immersive learning while investing in the next generation of cybersecurity leaders.
Now in its sixth year, Wicked6 has established itself as more than just a competition—it’s become a cornerstone in building a collaborative security community. The Women’s Society of Cyberjutsu, a national 501(c)(3) nonprofit that promotes training, mentoring, and advancement of women and girls in cybersecurity careers, has co-hosted the event since its inception. This year’s theme was leveling up, and the virtual format enabled unprecedented global participation with 31 speakers and over 500 participants of all skill levels from 48 countries.
Keynotes and sessions
The event kicked off with an upbeat introduction from Wicked6 emcee Kristin Demoranville, founder and CEO of AnzenSage, Jessica Gulick, Executive Director of Wicked6 and founder of Cyber Esports Foundation, and Mari Galloway, CEO of Women’s Society of Cyberjutsu. The trio emphasized the importance of programs such as Wicked6 that provide women with space and opportunities to learn and grow, strengthen our confidence, and celebrate each other’s contributions to the cybersecurity community.
Keynotes featuring speakers from Africa, Australia, Japan, Saudi Arabia, and the US resonated with the multinational participants. Topics ranged from hacking and protecting AI in the age of large language models (LLMs) to drawing inspiration from science fiction novels, with an eye toward boosting skills.
In his introduction to keynote speaker Anna Collard, SVP of Content Strategy and Evangelist at KnowBe4 Africa, Hart Rossman, Global Security Services Vice President at AWS, noted the positive impact of time invested by Wicked6 participants and supporters. He pointed out that the opportunity the event provides to build relationships and practice both soft skills and technical skills is a great example of what it means to build strong security culture.
“At AWS, we recognize that security is a team sport. It’s about building community and raising the bar together, so we can overcome determined adversaries and make all of our customers, colleagues, and communities safer.” —Hart Rossman, Global Security Services Vice President at AWS
Technical sessions included a presentation focused on safeguarding Amazon Simple Storage Service (Amazon S3) buckets by two AWS women in security, Customer Incident Response Team (CIRT) Responder Jennifer Paz and Worldwide Specialist Security Solutions Architect Shahna Campbell. Paz and Campbell detailed an unusual increase of data encryption events in S3 buckets that used an encryption method known as server-side encryption using client-provided keys (SSE-C). This activity, which was recently detected by the AWS CIRT team and its automated security monitoring systems, has been attributed to malicious actors who obtained valid customer credentials and were using them to re-encrypt objects. Paz and Campbell demonstrated how collective security awareness and best practices can help prevent unauthorized access to S3 buckets and protect against ransomware events that abuse stolen credentials. Details of their investigation and prescriptive guidance for helping to prevent unintended encryption of Amazon S3 objects are available in a related AWS Security Blog post.
Gamified learning
A security-focused AWS Jam was integrated into Wicked6 for a unique, gamified learning experience. With AWS Jam, individuals and teams compete to solve a series of technical challenges in a lab-based cloud infrastructure that enhances practical understanding of AWS services and best practices. Additionally, Wicked6 participants had access to 11 different cybergame services, including Hack The Box, Haiku, InspireTech, and MetaCTF, fostering a collaborative learning environment where security practitioners at all levels could grow together.
An AWS GameDay during the event also focused on enhancing cloud security skills. Led by AWS ProServe Security and AWS Support experts Jonas Buecker, Hicham Terkiba, and Makendran Gunasekaran, the games focused on network security (including network log inspections), identity and access management (IAM) policies, and using application security techniques and AWS Web Application Firewall (AWS WAF) to help prevent SQL injections. One participant enthusiastically commented, “This was an amazing opportunity to practice hands-on AWS security learning,” underscoring the unique value of the experience.
Investing in tomorrow’s security leaders
AWS partnered to donate event tickets to South Africa’s MiDO Academy, which aims to create pathways out of poverty and meaningful employment opportunities for young people, while alleviating the pressures felt by business owners to upskill and integrate new cybersecurity talent. Dale Simons, CEO of MiDO Academy said, “The sponsored tickets from AWS didn’t just provide access to training—they gave our students entry into a global security community. Our young women now see themselves as part of a larger security mission, understanding that their contributions to cybersecurity can have worldwide impact.”
By combining technical challenges with mentorship and collaboration, Wicked6 helped participants work together to upskill and address tomorrow’s challenges. Gulick highlighted the event’s impact, stating “Wicked6 2025 was a success. Each year, women from all over the world join us for speakers, games, and networking. By learning to play cybersecurity games, these women can leverage games to learn new tech skills throughout their careers.”
No matter your role—whether you’re a seasoned professional or just starting your cybersecurity journey—continuous learning is key.
“It’s important as women and as cybersecurity professionals not to get comfortable with the status quo. Leveling up means stepping out of our comfort zones and doing things that scare us. Going to networking events, actively talking with people, connecting with people on LinkedIn, getting educated to improve skills, and putting ourselves out there. Wicked6 is the perfect place to do that this year and in the years to come!” —Mari Galloway, CEO of Women’s Society of Cyberjutsu
Pursuing the path to success
As cyber threats continue to evolve, AWS remains committed to strengthening global security culture through initiatives that promote active participation and partnership. This year’s Wicked6 Cyber Games exemplified how the security community can encourage and support future leaders with collaborative learning experiences and foster a more resilient and adaptable workforce.
If you have feedback about this blog post, submit comments in the Comments section below. You can also start a new thread on the AWS Security, Identity, and Compliance re:Post to get answers from the community.
Software engineering stands at an inflection point. While previous technological shifts enhanced what developers could build, AI is fundamentally changing how we build. Amazon Q has driven a shift in how developers at Amazon approach software development. At re:Invent 2024, our breakout session Unleashing generative AI: Amazon’s journey with Amazon Q Developer (DOP214) shared insights from Amazon’s internal journey that reveal not just tactical benefits, but our strategic reimagining of the software development process itself. In the months since our talk, the capabilities of this technology have only accelerated in sophistication and reliability. Our hope is that these learnings can inform the approaches organizations are taking to adopt AI, through guidance on scaling implementation, measuring impact and considerations around meaningful data, and best practices every step of the way. For all of us, this is just the beginning of what is looking to be a very exciting journey as AI becomes not only an active assistant in our day-to-day innovation, but starts to become a peer and companion as AI agents take on full tasks.
Rethinking our mental models: The Productivity Paradox
For too long, we’ve approached software development optimization through the lens of industrial-age thinking – treating code like widgets on an assembly line. This mental model has led organizations to chase simplified metrics like lines of code or story points, missing the true nature of software development as knowledge work.
Our experience at Amazon has shown that the real opportunity isn’t just about making current processes faster – it’s about changing how developers interact with code, documentation, and knowledge. In the 2024 Stack Overflow Developer Survey, 53% of respondents agreed that waiting on answers disrupts their workflow, even if they know where to go find those answers. Similarly, 30% of respondents said knowledge silos impact their productivity ten times or more per week.
In 2024, to solve this problem for Amazon developers, we ingested our internal Amazon knowledge repository consisting of millions of documents into Amazon Q Business so our developers could get answers based on information spread across those repositories. By simply asking Amazon Q their questions in existing tooling instead of manually searching or needing to ask an expert, we reduced the time Amazon developers spent waiting for technical answers by over 450k hours and reduced the interruptions to “flow state” of existing team members.
Today’s developers face a striking paradox: while they’re equipped with more powerful tools than ever, we know that across the industry, developers can spend only 1-2 hours daily writing code. The rest is consumed by what we call “toil” – necessary but undifferentiated work that scales linearly with software complexity. This represents not just a productivity challenge, but a strategic liability for organizations trying to accelerate innovation.
Amazon’s scale has provided unique insights into the transformative potential of AI in software engineering. Using AI for software transformations tied tightly into our internal development tools, we didn’t just save 4,500 developer years of effort – we unlocked new possibilities for large-scale technical modernization that previously seemed impractical. This experience revealed something profound: AI isn’t just making existing processes more efficient; it’s making previously impossible tasks feasible. For instance, our ability to automatically handle complex dependency updates across thousands of services has fundamentally changed how we think about technical debt and system modernization. Over the coming years as these AI agents become increasingly capable and autonomous, we will get increasingly bold with the types of modernization work we ask them to perform, ensuring reliability by complementing them with other agentic capabilities such as correctness validation, testing, and even advanced anomaly detection and production system operations.
The evolution of developer cognition
Perhaps the most fascinating insight from our journey has been observing how AI is changing the way developers think about and solve problems. The traditional model of a developer working in isolation, relying solely on their own knowledge and documentation, is evolving into a more collaborative model where AI serves as an intelligent thinking partner. We’ve seen this manifest in unexpected ways. Developers report that having AI tools available changes not just how they write code, but how they approach problem-solving itself. The ability to rapidly explore multiple approaches or instantly access contextual knowledge has enabled more creative and experimental development practices.
In particular, we are seeing seasoned developers playing with new-to-them programming languages and coding techniques that previously would not have been worthwhile due to ramp time. One developer reported cutting their typical three-week ramp-up time for learning a new programming language down to just one week using Q Developer. This significant reduction in a developer’s initial time investment allows creativity with more suitable programming languages for nuanced project requirements, or jumping into work with unfamiliar and complex systems, without sacrificing code quality. For example, with our recently launched Amazon Q Developer Agentic CLI, another internal developer was able to work with an unfamiliar codebase to build and implement a non-trivial feature within 2 days using Rust, a programming language they didn’t know, stating, “If I’d done this ‘the old fashioned way,’ I would estimate it would have taken me 5-6 weeks due to language and codebase ramp up time. More realistically, I wouldn’t have done it at all, because I don’t have that kind of time to devote.”
As we look to the future, we see several emerging frontiers that will further transform software engineering. The rise of AI agents capable of handling increasingly complex development tasks is shifting the developer’s role from implementation to orchestration. We’re moving toward a model where developers spend more time defining what needs to be built and validating approaches, rather than handling every implementation detail. System architecture, traditionally considered too nuanced for automation, is emerging as a new frontier for AI assistance. Application security reviews or software testing, frequent bottlenecks to software release due to specialist bandwidth, will increasingly be accelerated by AI agents amplifying the capacity of those specialists. While we’re just beginning to explore this space, early experiments suggest AI could help architects evaluate trade-offs and identify potential issues in complex systems more effectively than ever before.
Strategic implications for organizations
We believe the most successful organizations will be those that view AI not just as a tool for automation, but as a catalyst for transforming how they approach software development entirely. The real strategic advantage will come from reimagining software development processes and culture to fully leverage AI’s capabilities. This includes rethinking traditional metrics, redefining developer productivity, and creating space and cultural change for teams to experiment with new ways of working. Amazon Q represents a new class of development tools that augment developer capabilities in fundamental ways, beyond just writing code more efficiently. Organizations that understand and embrace this transformation will be best positioned to lead in the next era of software innovation.
To learn more about Amazon Q Developer and explore innovative ways of accelerating software development refer to the Q Developer documentation. Individual users can get started with Q Developer in the AWS Console, CLI, or in their IDE on the perpetual Free Tier. And remember: give yourself and your team “Permission to Play!” We’re at the heart of a technological revolution; as technologists this a moment where we get to immerse ourselves in the unknown and learn and be curious!
Increasing developer productivity has been a persistent challenge for senior leaders over the past decades. With the rise of generative artificial intelligence (AI), a new wave of innovation is transforming how software teams work. Generative AI tools like Amazon Q Developer are emerging as game-changers, supporting developers across the entire software development lifecycle. But how are large-scale organizations successfully adopting this AI-assisted approach? This document shares good practices I have discovered through working with enterprise customers navigating this technological transformation.
A common misperception still is that a developer is more productive when they write code faster. But a median developer spends less than one hour per day writing code, as a study conducted by software.com in 2022 shows. This makes clear that there are other aspects to consider when it comes to building an application and running it in production. Generative AI tools for developers, such as Amazon Q Developer, started as coding companions that provided inline completions. As the technology evolved, Amazon Q Developer is now able to support developers across the entire software development life cycle.
The Change Challenge
Generative AI offers new and interesting ways for developers to solve challenges and to support them in their daily work. But taking advantage of those opportunities takes some time. It introduces a noticeable change to their familiar ways of working and therefore it is much about forming a new habit. This, according to science, usually takes a minimum of two months. Teams need the space and permission to play with this new approach and to find out what works best for them. Expecting them to adopt a new way of working while expecting the same (or higher) level of output at the same time will only lead to teams falling back to what they know works. For customers that successfully have adopted Amazon Q Developer I have seen them reducing the delivery expectations to give space to learn, and having required teams to share learnings in return.
Additionally, as in any other large change project there is a significant cultural aspect to consider. If people feel intrinsically convinced by the value and benefits of an AI-supported approach to software engineering they will use it. “Simply ordering from above” will not help making an adoption successful. But building community, experimenting, learning, and sharing successes will. “Culture eats strategy for breakfast”, as the management visionary Peter Drucker said.
Keeping that in mind it is clear that there is no one-size-fits-all prescriptive way of successfully introducing generative AI tools for developers in your organization. It very much depends on your individual culture, goals, challenges, people, skills, and technology stack for example. However, there are a number of principles and good practices that work well with several of our large-scale customers who have successfully adopted Amazon Q Developer.
Best Practices for Successful Adoption
The following illustration describes the change management cycle and recommended activities for adopting AI-assisted software development.
Figure 1. The change management cycle
1. Secure Top-Down Commitment
Secure executive buy-in for adopting AI-assisted software development because this is a powerful sign for the organization. It helps to remove roadblocks and to promote successes across the organization. An executive sponsor links the adoption of AI-assisted software development to the strategic goals of the organization, will help resolving prioritization and capacity conflicts. Invite the sponsor to a kick-off meeting. Include them for the discussion of goals and success criteria, and keep them updated on progress, success stories, and challenges.
2. Become Clear on Goals and Success Criteria
Simply rolling out Generative AI tools to a large developer base won’t be enough. You need to be clear what you expect from such an adoption for your organization, for your developers, and for your business. It is important for you to understand your organization’s pain points from a developer experience perspective and how they affect your development productivity. These likely differ between different personas, like Software Developers and DevOps Engineers. For example, are your applications lacking test coverage or is your code lacking documentation, which creates a maintenance burden, and makes it difficult to onboard new developers? Is handling legacy code risky and time-consuming so that you avoid necessary upgrades because of the complexity and effort? Is troubleshooting applications locally or in production eating up your developers’ time? Or are you facing challenges caused by hard-to-find security issues in the code? What is it that you want to achieve by introducing an AI-assisted development approach, and why?
3. Establish Ownership
Adopting a new approach like the use of generative AI in software development at scale leads to many change management and coordination tasks. Those are related to getting access to the tool, enablement for new users, budget planning, measuring success and creating transparency on problems, creating momentum and making sure the adoption sustains, amongst others. Therefore, introducing a Customer Champion as a leader who coordinates the business and technology related aspects of the adoption is a common approach. They will connect the strategic goals of the organization with the tactical activities necessary for the implementation. If your adoption is spanning multiple different business units with larger developer bases consider establishing this role for each of them, forming a team that collaborates across your whole organization. Key responsibilities of the Customer Champion are to bring the right people together to successfully work on the adoption, to create transparency on status, and to address impediments early on.
4. Introduce Metrics
Once you have gained clarity on the specific pain points and goals for your organization, the next step is to determine the appropriate metrics to measure the success of your efforts. For example, you can measure the impact of using Amazon Q Developer on onboarding new developers by tracking the time to first commit against a previously established baseline average. Comparing the time it takes to complete certain tasks – like writing and integrating code, fixing bugs, setting up or upgrading environments, the time it takes to build a new feature, or by comparing sprint velocity before and after the introduction of Amazon Q Developer will give you further indications. But keep in mind that there is ambiguity in these metrics because they are impacted by different factors.
Focusing on developer experience and productivity, monitor the development of your established measurement framework, like DORA, SPACE, or GSM. SPACE in particular, with its “Satisfaction & Well-Being” dimension, pays close attention to how software developers perceive their work and how satisfied they are with their own productivity. Tools like Amazon Q Developer have shown a positive effect here, as for example a McKinsey study shows. They help to free developers from tasks that are perceived as toil, like repetitive and boring grunt work that doesn’t necessarily bring business value. To measure this impact on perceived productivity, customers sometimes design simple surveys, asking developers questions like “in percentage, how would you estimate the impact of using Amazon Q Developer on your productivity” or “on a scale from 1-5, how is Amazon Q Developer impacting the satisfaction with your day-to-day work?”
As a last dimension, understanding the general usage of Amazon Q Developer across your organization is important. Monitor the number active subscriptions, accepted code recommendations, or the number of executed security scans from the Amazon Q Developer dashboard. That way you will get an understanding for the acceptance of the tool in your developer base. Correlate this information with the success metrics you defined.
5. Start Small
When “rolling out” an AI-assisted software development approach, keep the technology adoption lifecycle and Everett Roger’s bell curve in mind. It describes that adoption of a new technology usually starts with a few “innovators”, followed by a small fraction of “early adopters”. Only if those early groups demonstrate convincing success, the majority of users will follow the adoption. To settle on this model will help you making the adoption of AI-assisted development successful in your organization.
Start small. Identify your tech innovators, or champions, who are enthusiastic to support the introduction of Amazon Q Developer and to advocate the approach in your organization. With them, build a team or a Center of Excellence (COE) that will help with identifying early adopters across your development teams, building technical and enablement foundations for onboarding users, creating roll-out plans, and evangelizing and sustaining the adoption. The champions will act as a bridge between your adoption program team and your users. They can provide insights and feedback on the adoption and come up with recommendations.
6. Create Momentum
Now that you have your foundations in place it is time to create momentum and onboard your early adopters to Amazon Q Developer. Start with a communication plan to raise awareness, to share updates and success stories, and to collect feedback from the users. You will need to create training material covering organization-specific resources (how to get access, for example, or which communication channels and contact points exist), user guides, tutorials, and pointers to relevant documentation and online resources. Consider creating your own prompt library, documenting prompts for Amazon Q Developer that your users find particularly helpful. There are community projects like promptz.dev that can deliver inspiration. Especially for new users this will have a lot of value for getting up to speed.
Consider how to integrate learning pathways with your organization’s learning platform moving forward. These should include the company-specific experience and knowledge you collect. In addition, it might be helpful to integrate external offers, like classroom trainings or workshop formats offered by AWS.
Hands-on technical enablement workshops will help your early adopters jumpstarting their experience. AWS offers multiple formats that can be tailored to your individual context. These include service deep-dives with Amazon Q Developer specialists, Immersion Days and hackathon support for teams to hands-on experience the tool in a guided, interactive format, or joined proof-of-value engagements. Your AWS account team will provide you more information.
7. Sustain and Scale Adoption
At that point you will have established Amazon Q Developer among an initial segment of your developer base. However, keeping Roger’s adoption curve in mind the largest part of the adoption still lies ahead of you. To facilitate the it across your whole organization, focus on delivering enablement workshops for the teams to be onboarded. These will be led by your champions and incorporate your organization-specific practices and knowledge.
To sustain the adoption, make sure the existing user base stays active. Continue offering exchange and support, collecting feedback, updating your enablement material, sharing updates on the latest developments for Amazon Q Developer, and reviewing your metrics. Create visibility across your organization for the accomplishments and positive experiences. Let user talk about the impact Amazon Q Developer has on their work. This will help building momentum. Nurture community building around your users of AI-assisted development.
Establish regular office hours with your champions for providing support and enablement to your users of Amazon Q Developer. This will facilitate the continuous gathering of feedback to improve documentation and enablement materials, collect and promote success stories, and validate the adoption approach. Additionally, establish a consistent communications and reporting cadence to keep all relevant stakeholders informed of key metrics, updates, feedback, and success stories. This ensures the alignment of the adoption of AI-assisted development with your strategic goals and expectations.
8. Inspect and Adapt
In addition, keep reflecting on the goals and metrics you came up with from a strategic perspective. Are they developing in the right direction? Are your pain points still the same? Should you move your focus to different aspects of the software development life cycle? And how might new capabilities of Amazon Q Developer support your goals?
Conclusion
By following the outlined approach, large organizations can successfully navigate the challenges of adopting Amazon Q Developer. The approach addresses technical, cultural, and organizational aspects of the adoption, increasing the likelihood of realizing the full potential of AI-assisted development across the enterprise.
If you are looking for advice or support during your adoption journey, your AWS Account Team will connect you with experts on Amazon Q Developer, provide you information on training and enablement, and support you with setting up a successful rollout program for your organization. To learn more about how Amazon Q Developer’s capabilities support the whole software development lifecycle, visit the product page or have a look at the documentation.
About the Author
Rene-Martin Tudyka is a Senior Customer Solutions Manager at AWS and provides guidance and support for enterprise customers on their cloud maturity journey. He has a long background in developing highly performant IT organizations and in successful large-scale cloud adoption.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.

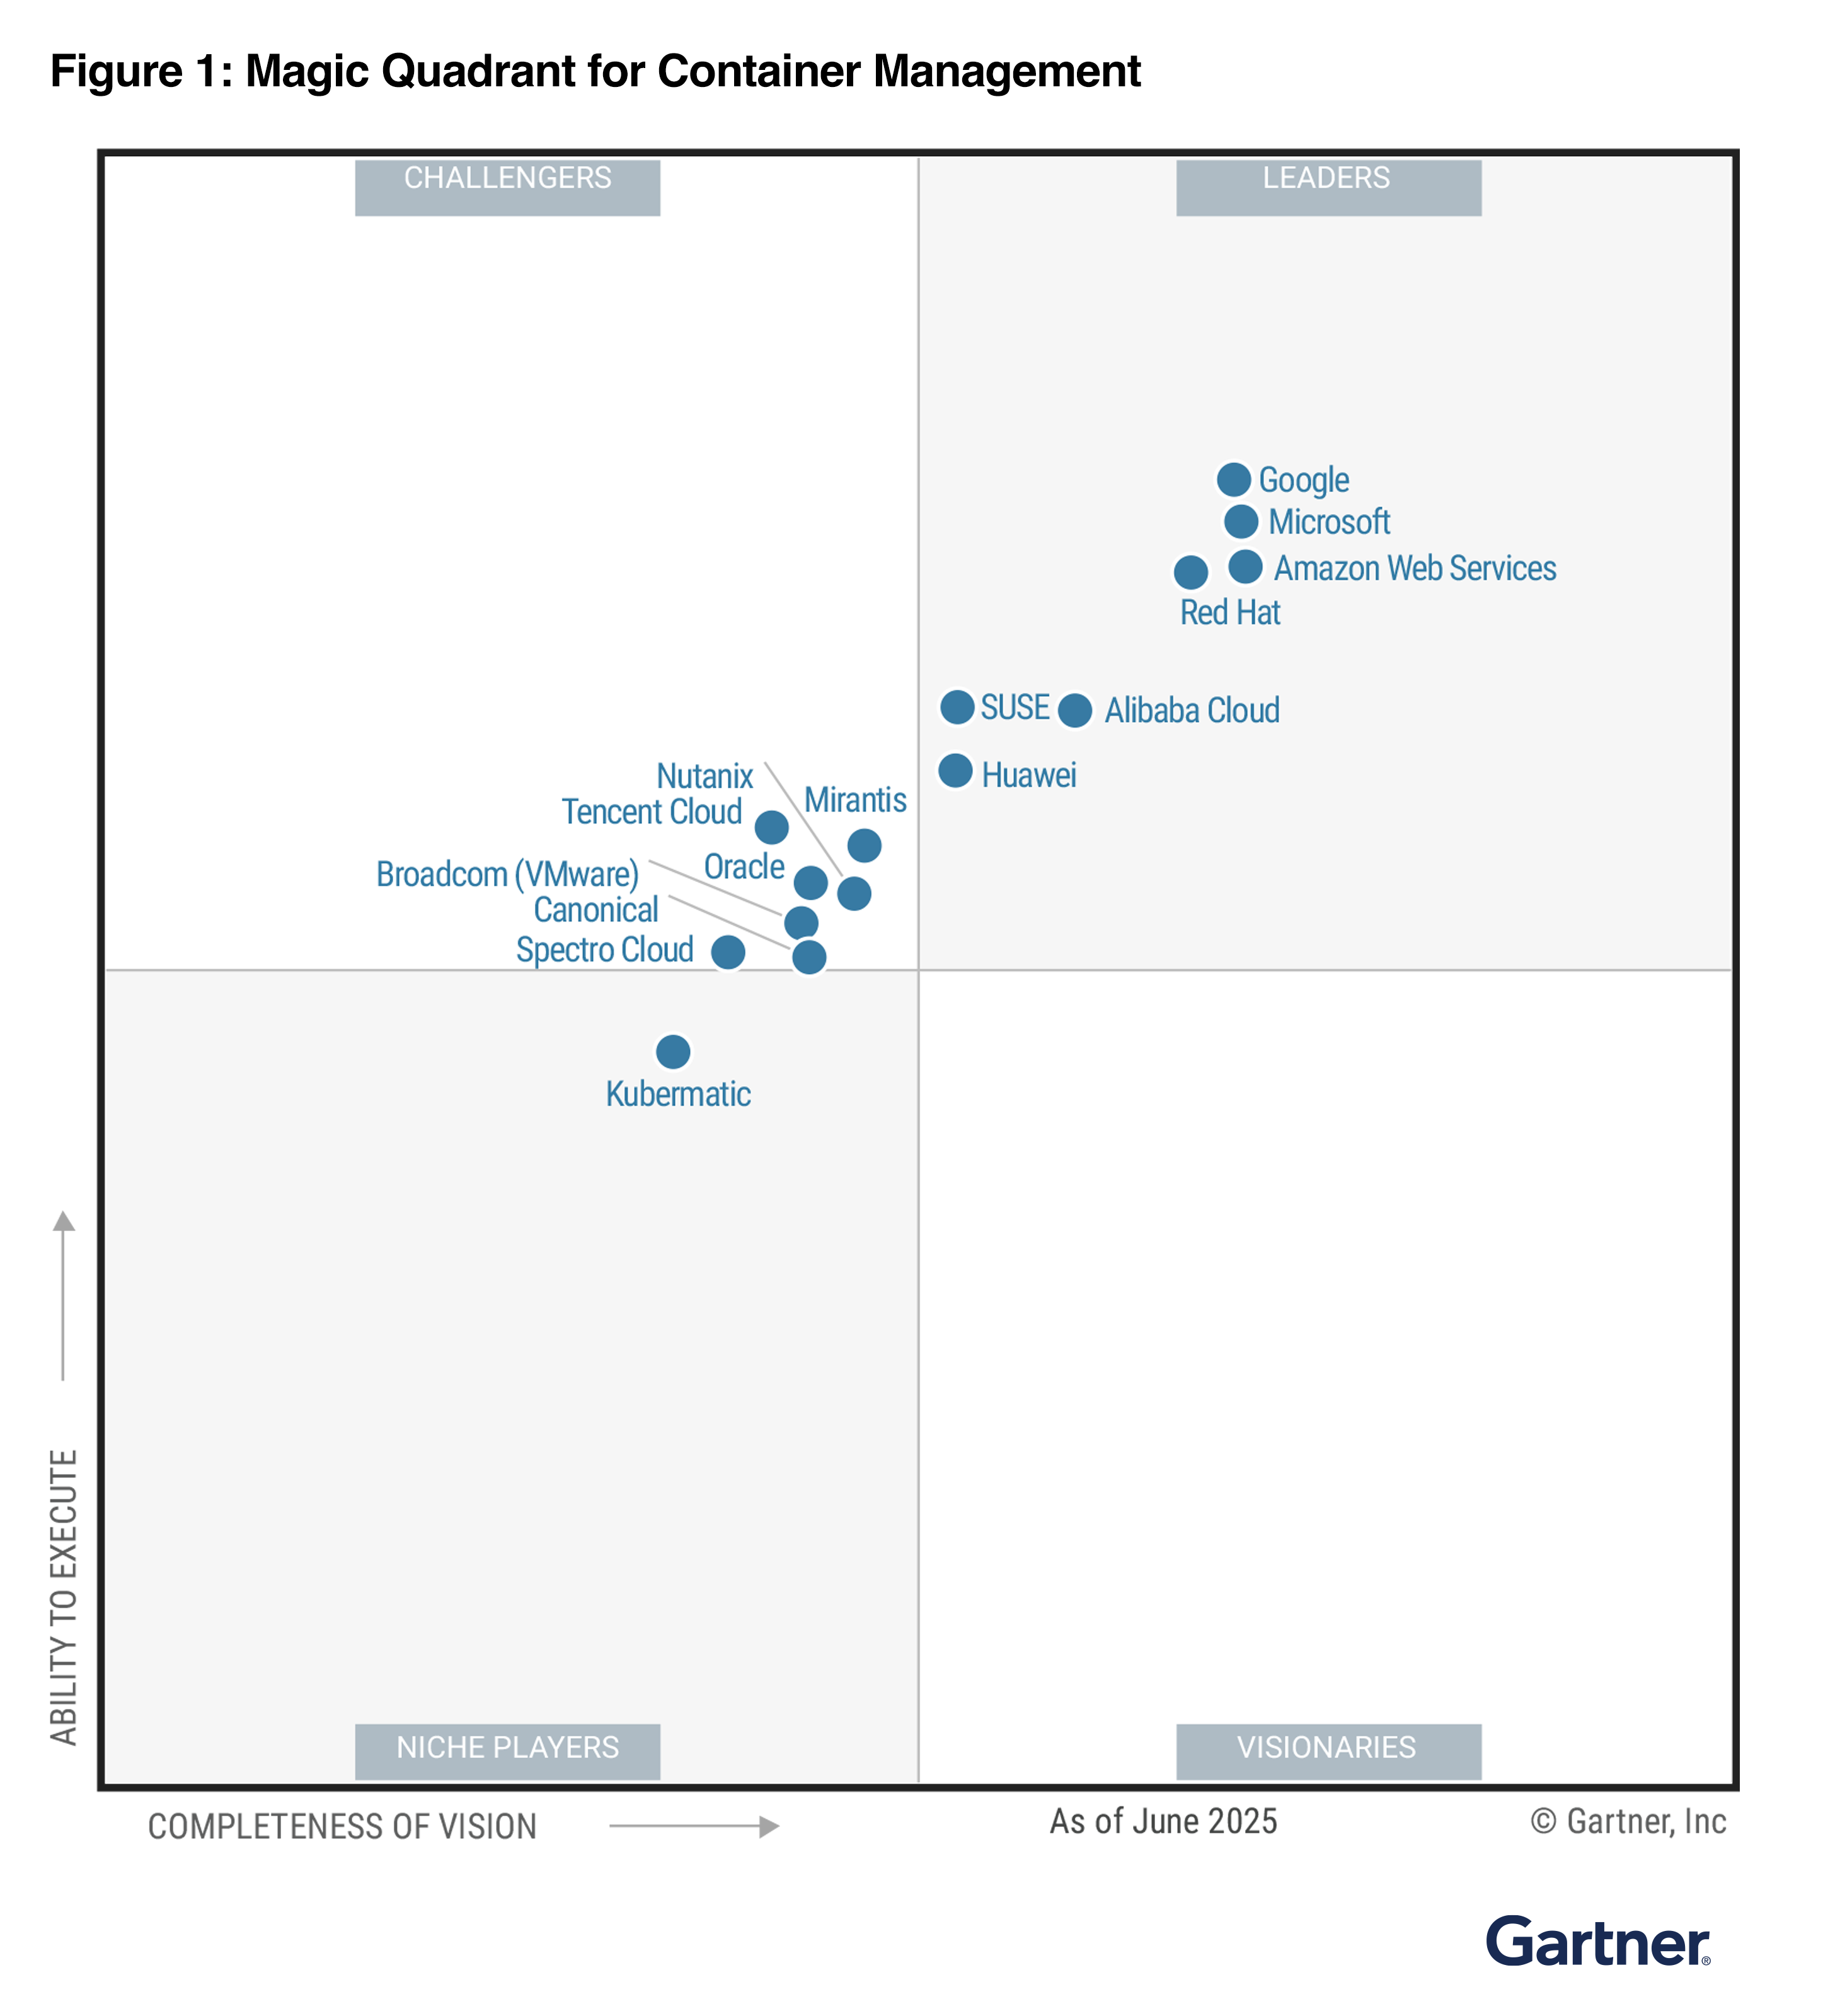
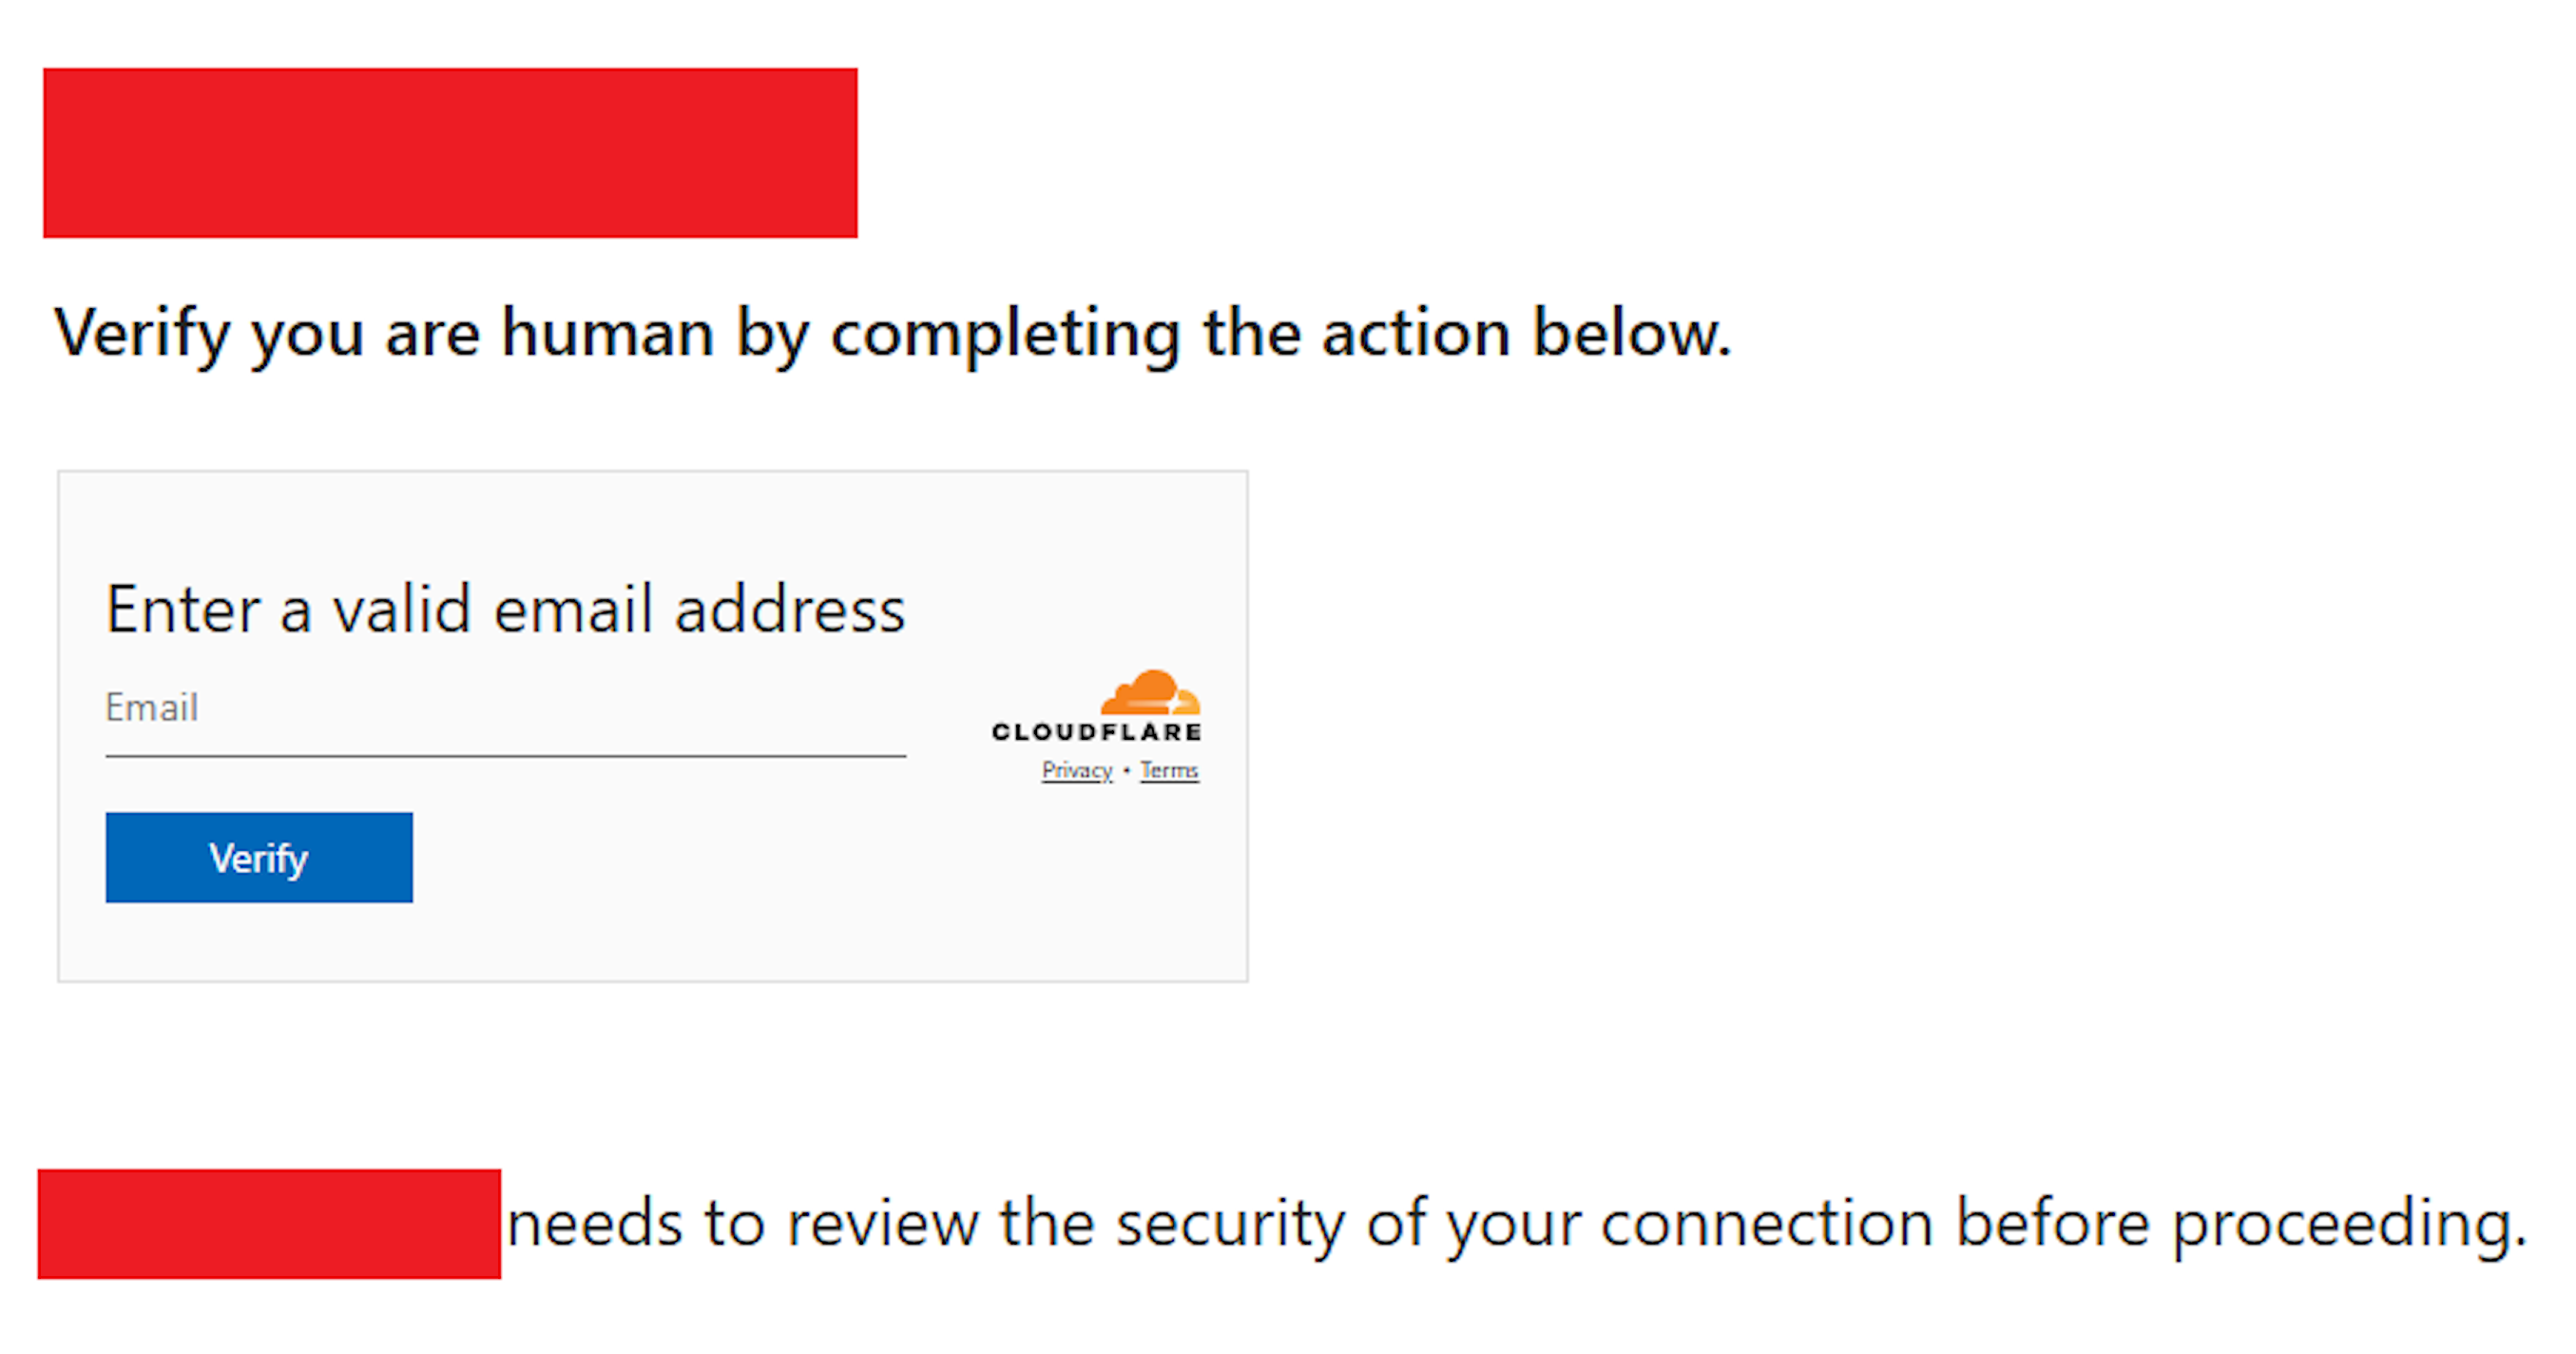

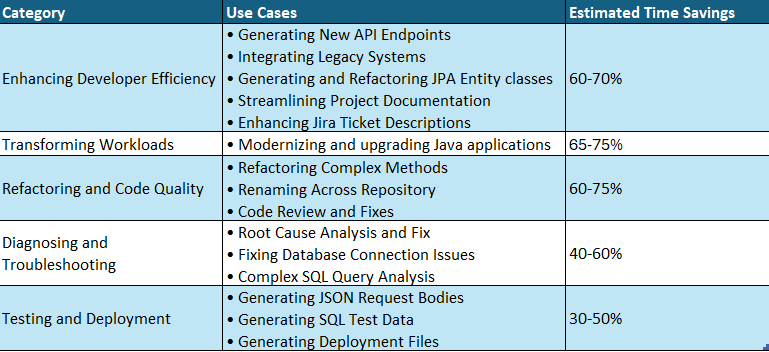
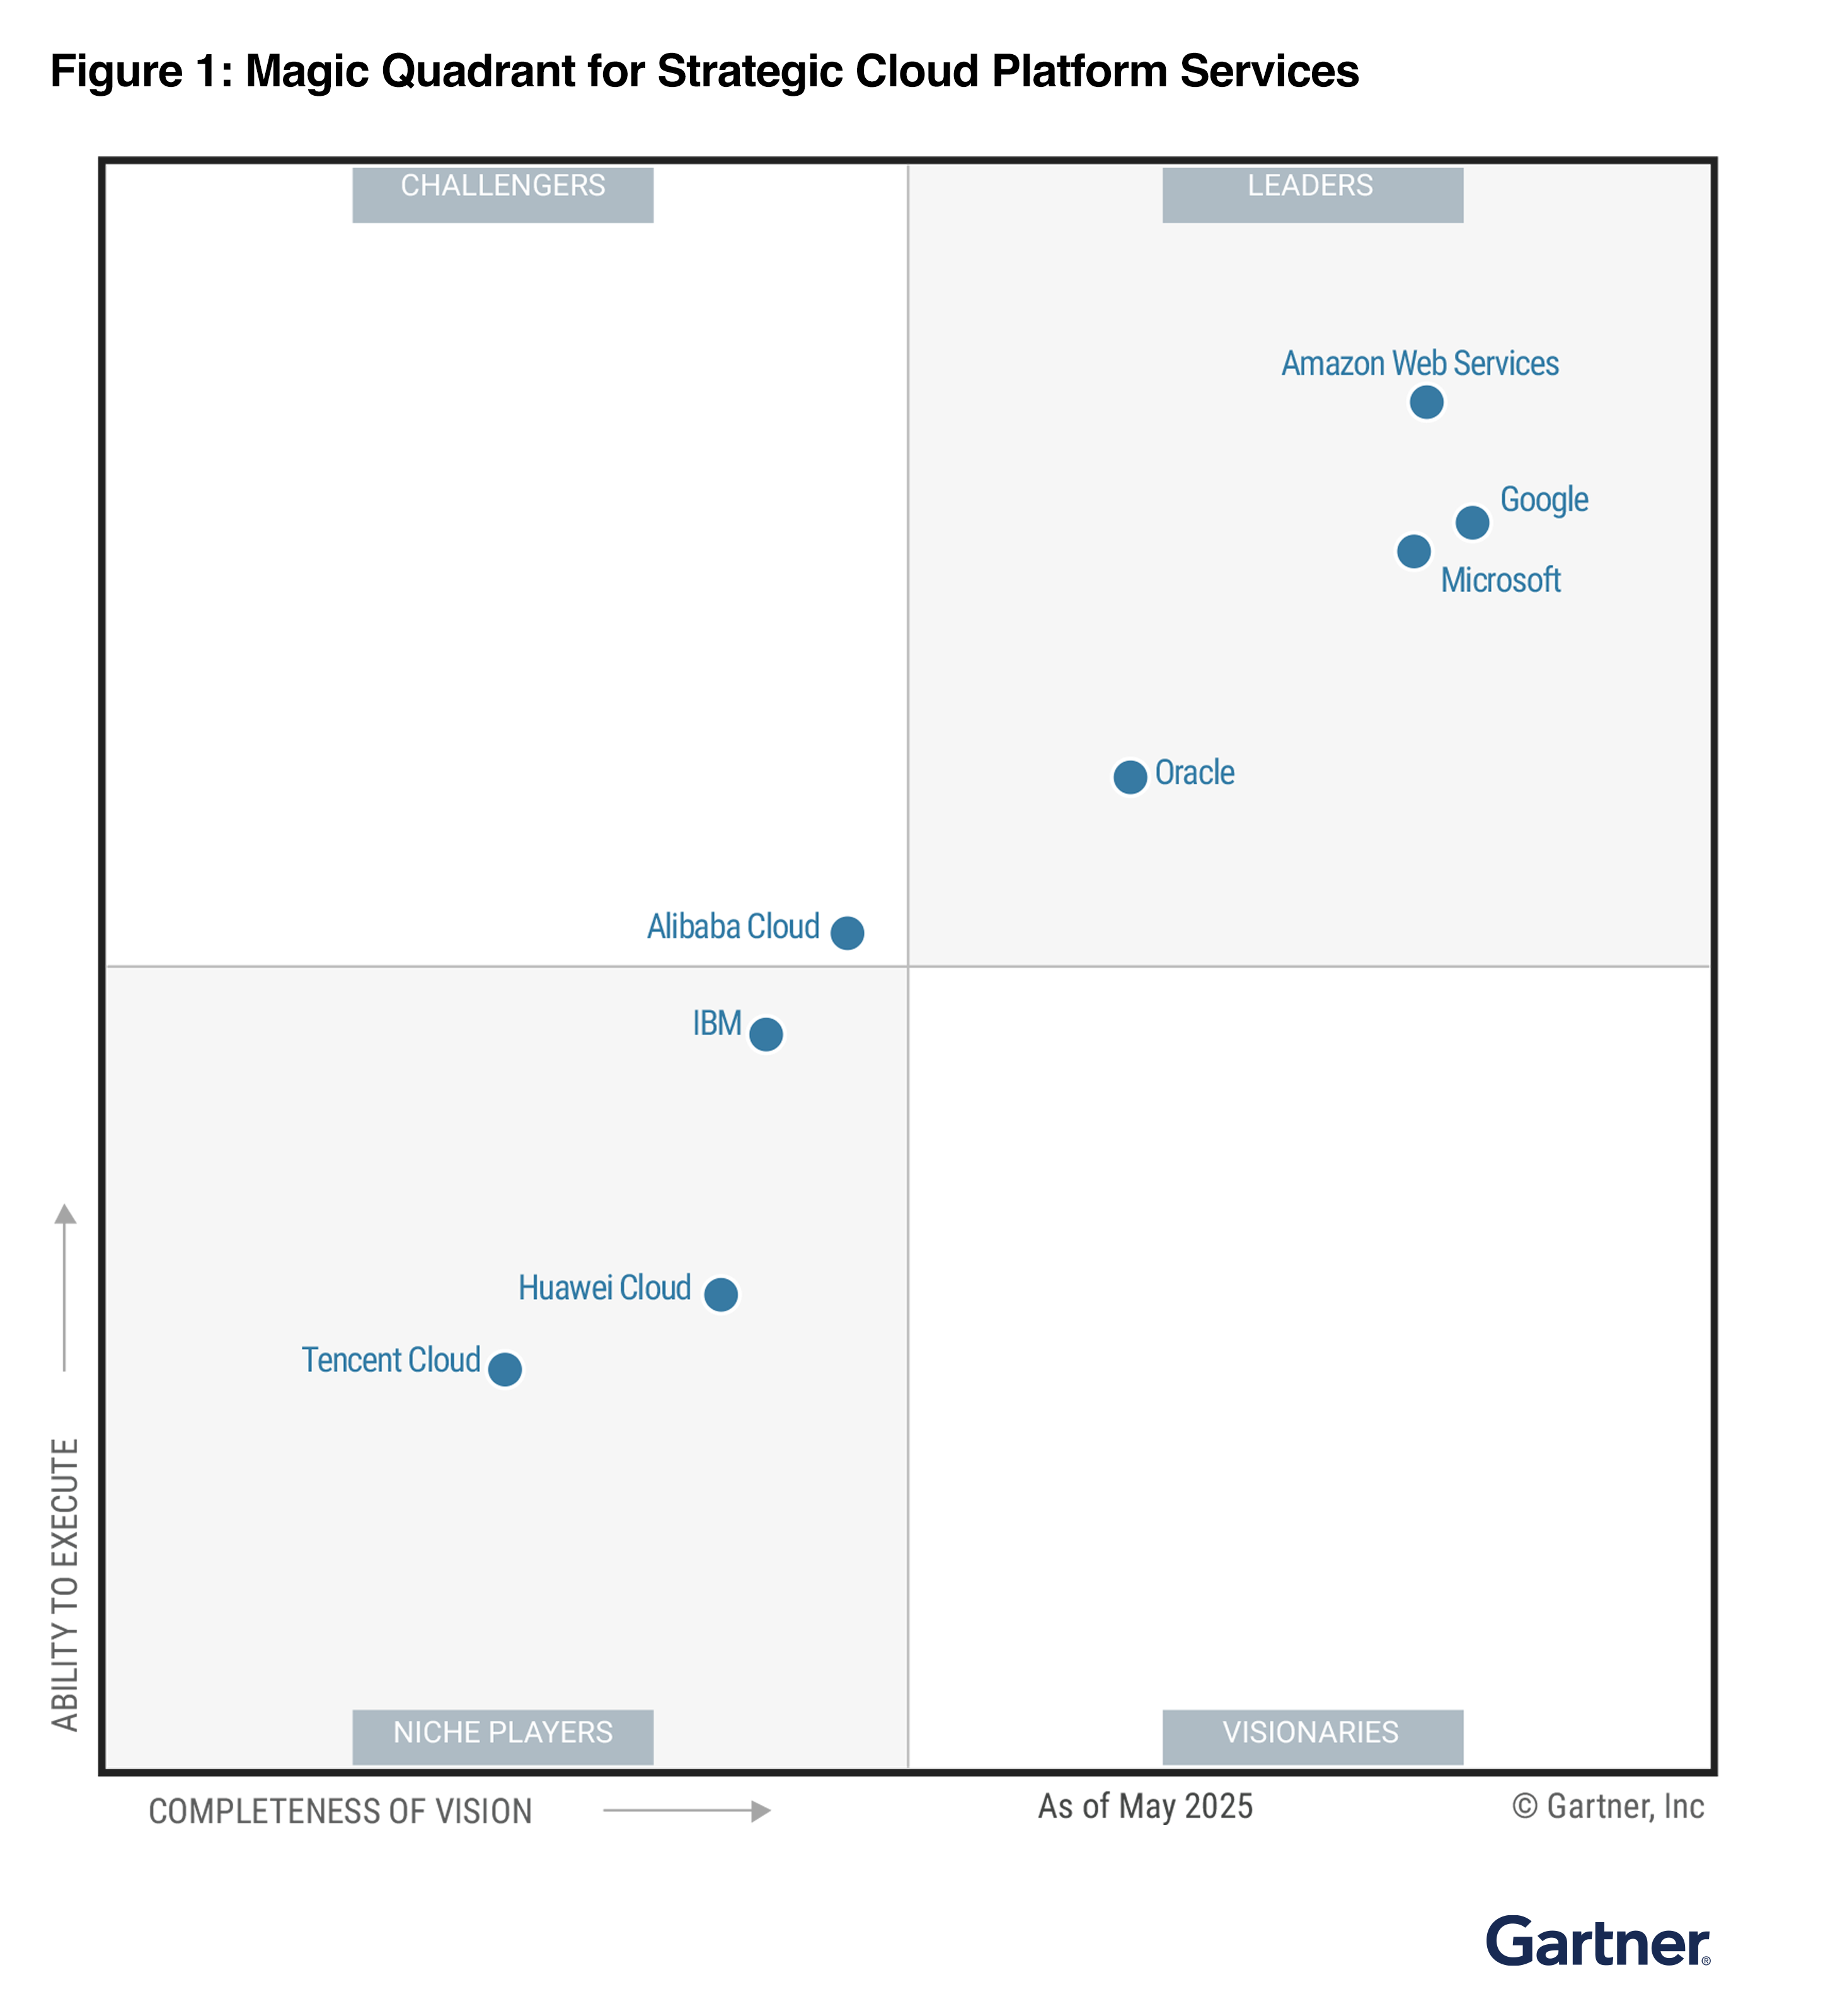
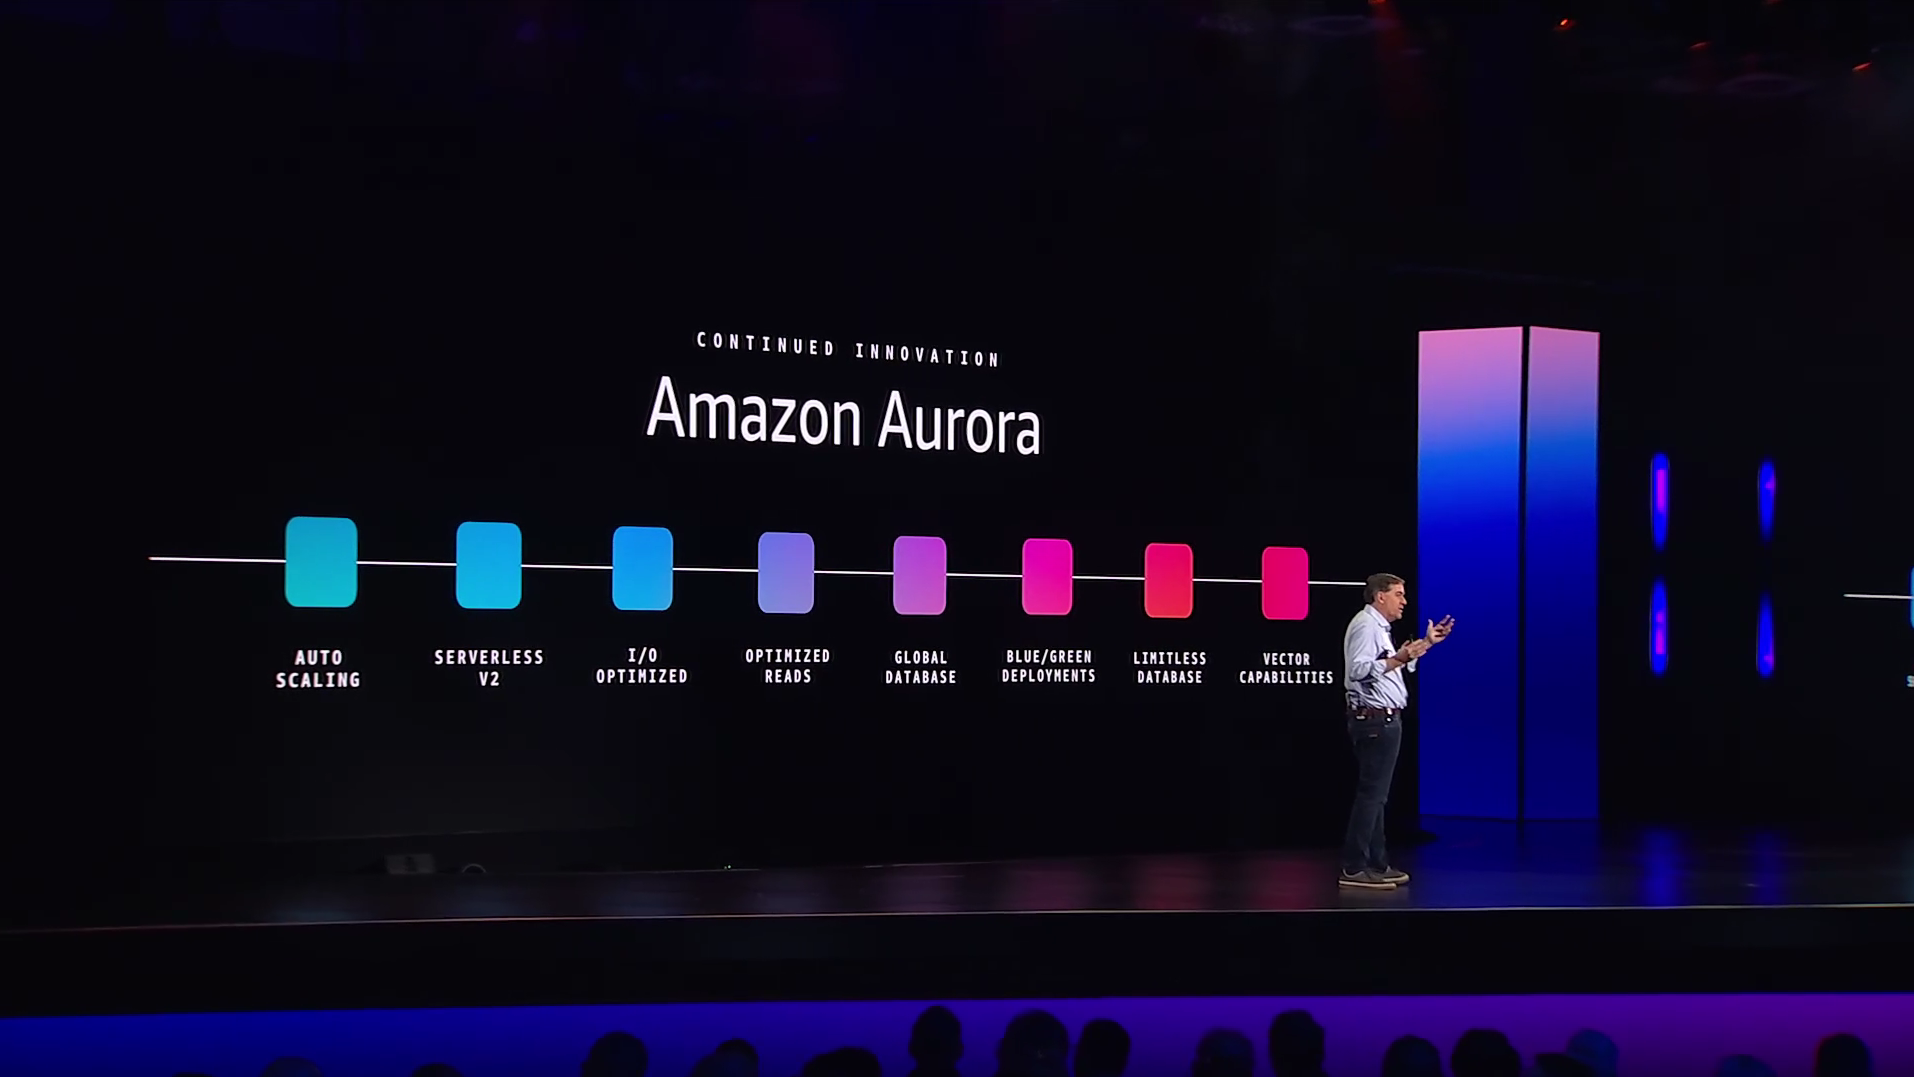
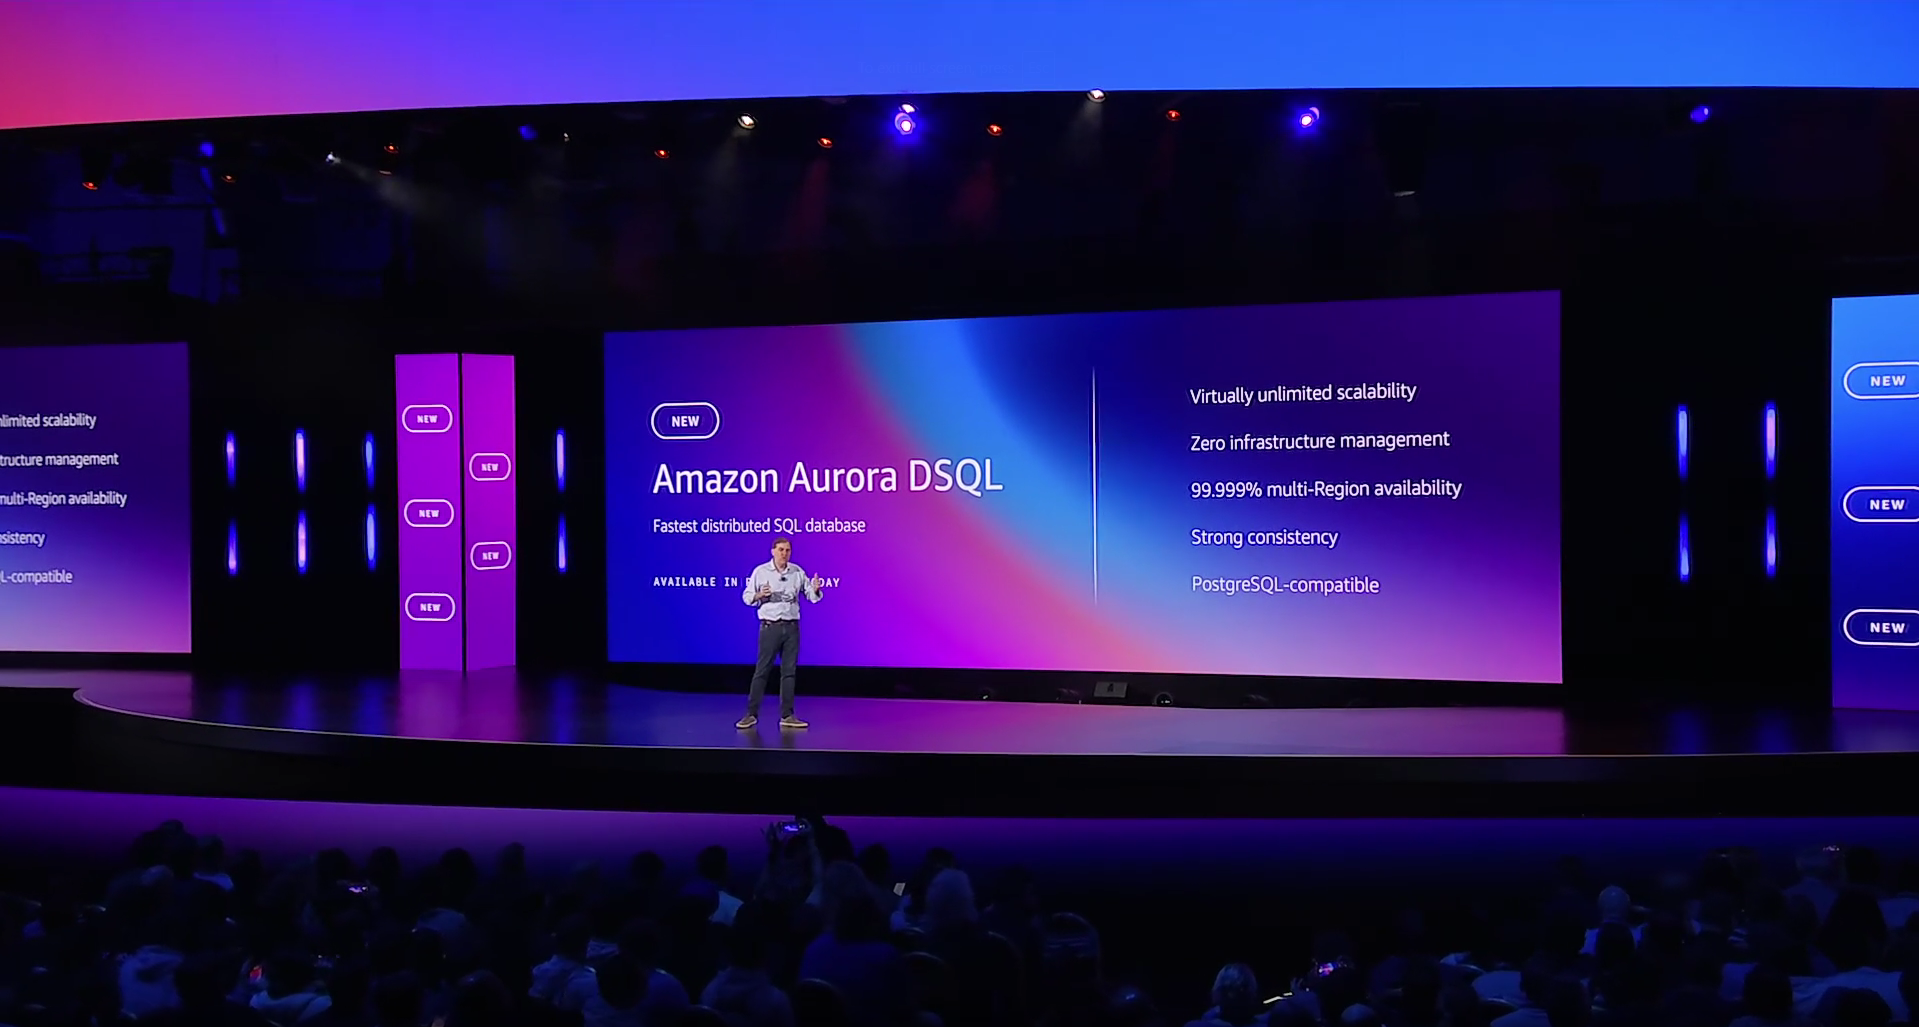




 Amit Maindola is a Senior Data Architect focused on data engineering, analytics, and AI/ML at Amazon Web Services. He helps customers in their digital transformation journey and enables them to build highly scalable, robust, and secure cloud-based analytical solutions on AWS to gain timely insights and make critical business decisions.
 Srinivas Kandi is a Senior Architect at Stifel focusing on delivering the next generation of cloud data platform on AWS. Prior to joining Stifel, Srini was a delivery specialist in cloud data analytics at AWS helping several customers in their transformational journey into AWS cloud. In his free time, Srini likes to explore cooking, travel and learn new trends and innovations in AI and cloud computing.
 Hossein Johari is a seasoned data and analytics leader with over 25 years of experience architecting enterprise-scale platforms. As Lead and Senior Architect at Stifel Financial Corp. in St. Louis, Missouri, he spearheads initiatives in Data Platforms and Strategic Solutions, driving the design and implementation of innovative frameworks that support enterprise-wide analytics, strategic decision-making, and digital transformation. Known for aligning technical vision with business objectives, he works closely with cross-functional teams to deliver scalable, forward-looking solutions that advance organizational agility and performance.
 Ahmad Rawashdeh is a Senior Architect at Stifel Financial. He supports Stifel and its clients in designing, implementing, and building scalable and reliable data architectures on Amazon Web Services (AWS), with a strong focus on data lake strategies, database services, and efficient data ingestion and transformation pipelines.
 Lei Meng is a data architect at Stifel. His focus is working in designing and implementing scalable and secure data solutions on the AWS and helping Stifel’s cloud migration from on-premises systems.