Tag Archives: Advanced (300)

Building multi-tenant SaaS applications with AWS Lambda’s new tenant isolation mode

Post Syndicated from Anton Aleksandrov original https://aws.amazon.com/blogs/compute/building-multi-tenant-saas-applications-with-aws-lambdas-new-tenant-isolation-mode/

Today, AWS announced a new tenant isolation mode for AWS Lambda, that allows you to process function invocations in separate execution environments for each application end-user or tenant invoking your Lambda function. This capability simplifies building secure multi-tenant SaaS applications by managing tenant-level compute environment isolation and request routing for you. As a result, you can focus on your core business logic rather than implementing your own tenant-aware compute environment isolation.

Overview

Lambda runs your function code in secure execution environments that leverage Firecracker virtualization to provide isolation. These execution environments never share or reuse virtual resources (such as vCPU, disk, or memory) across functions, or even across different versions of the same function. However, Lambda can reuse execution environments for multiple invocations of the same function version, as these execution environments are fully set-up and can therefore deliver faster request processing for your functions.

Figure 1. Incoming invocations processed by a collection of execution environments that belong to a single function.

Figure 1. Incoming invocations processed by a collection of execution environments that belong to a single function.

Multi-tenant SaaS applications that handle sensitive tenant-specific data or execute code supplied dynamically by tenants may need a higher degree of isolation—at the individual application tenant level rather than at the function level—for secure code execution and to reduce the risk of cross-tenant data access.

Prior to today’s launch, developers would implement custom solutions, such as SDKs or application logic to manage isolation within function code. This approach was bug-prone, required more work from application development teams, and didn’t ensure isolation at the compute environment level.

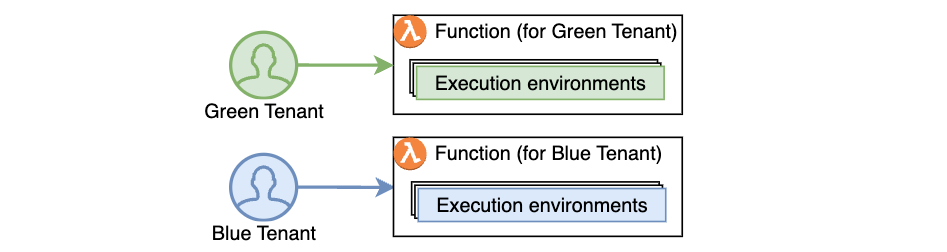
Alternatively, developers adopted the approach of creating separate functions per application tenant, replicating the same code across hundreds or thousands of tenants. This approach provided stronger compute environment isolation than sharing compute environments across multiple tenants of the same function, but increased implementation overhead and operational complexity as workloads grew to support a larger number of tenants over time.

Figure 2. Using function-per-tenant model, each tenant’s requests are processed by a separate function.

Figure 2. Using function-per-tenant model, each tenant’s requests are processed by a separate function.

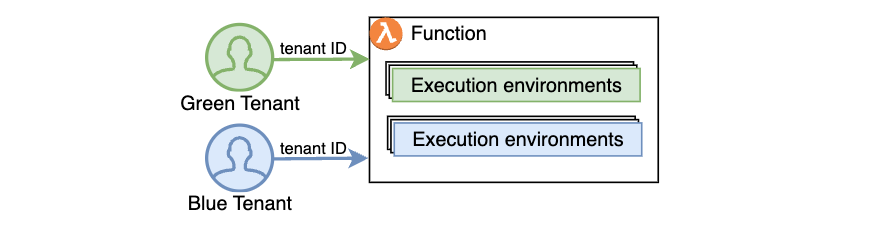
Starting today, AWS Lambda offers a new tenant isolation mode that lets you isolate execution environments used across different tenants of your multi-tenant SaaS applications, even when all of the tenants invoke the same function. When you enable the new tenant isolation mode, you include a tenant identifier with each function invocation. Lambda uses this identifier to route the request to the correct execution environment. As a result, each execution environment is reused only for invocations from the same tenant. This means you still get the performance benefits of warm execution environments, while ensuring that each tenant’s workloads remain isolated.

Figure 3. With the new tenant isolation capability, Lambda creates separate execution environments per tenant for a single function.

Figure 3. With the new tenant isolation capability, Lambda creates separate execution environments per tenant for a single function.

For organizations handling sensitive tenant-specific data or running untrusted code supplied dynamically by end-users, Lambda’s new tenant isolation mode provides the security benefits of per-tenant compute environment separation without the operational complexity of managing individual functions or infrastructure for each tenant.

Example scenario

Consider building a multi-tenant serverless SaaS application. To optimize performance, your function handler can retrieve tenant-specific configuration and data, cache it in memory, and reuse it for subsequent invocations from the same tenant. For example, you might cache tenant-specific database location, feature flags, or business rules that are frequently accessed during request processing. You may store this information within the application runtime process as global variables or as files in the /tmp directory. However, if the underlying execution environment is used to serve multiple tenants, this approach can potentially expose data across tenants.

With tenant isolation mode you can address this risk with much simpler architecture and configuration. This built-in capability makes Lambda an excellent choice for multi-tenant SaaS applications needing isolated compute environments for individual tenants.

Getting Started with Lambda Tenant Isolation Mode

Use the new tenancy-config parameter to configure tenant isolation mode when you create your function. You can only apply this configuration at function creation time; it cannot be updated for existing functions. The following snippet creates a function with tenancy config using the AWS CLI.

aws lambda create-function \
   --function-name my-function1 \
   --runtime nodejs22.x \
   --zip-file fileb://my-function1.zip \
   --handler index.handler \
   --role arn:aws:iam:1234567890:role/my-function-role \
   --tenancy-config '{"TenantIsolationMode": "PER_TENANT"}'

After the function is created, you must provide the tenant ID parameter with each invocation. Lambda uses this identifier to ensure that the execution environment used for a particular tenant is never reused for other tenants. For subsequent invocations from the same tenant, Lambda may reuse the execution environment to optimize performance. Specify this tenant-id parameter as illustrated below:

aws lambda invoke \
   --function-name my-function \
   --tenant-id BlueTenant \
   response.json

The new tenant-id parameter is required for functions using the tenant isolation mode. Function invocations omitting this parameter will fail with an invocation error, as shown below:

aws lambda invoke --function-name multitenant-function out.json

An error occurred (InvalidParameterValueException) when calling the Invoke operation:
The invoked function is enabled with tenancy configuration. 
Add a valid tenant ID in your request and try again.

Lambda makes the tenant ID parameter available through your function handler’s context object. This allows you to access tenant-specific information in your code, for example if you wish to implement custom logic based on the tenant identity, as shown below:

exports.handler = async function (event, context) {
   const tenantId = context.tenantId;

   // Process tenant-specific logic

   return {
      statusCode: 200,
      body: `OK for tenantId=${tenantId}`
   };
};

The following table outlines differences between Lambda functions with and without tenant isolation mode enabled:

Feature Without the new
tenant isolation mode
With the new
tenant isolation mode
Execution environment isolation Isolated per function version. Isolated per end-user or tenant invoking a function version.
Execution environment reuse Can be reused to process all invocations of a function version. Can only be reused to process invocations from the same tenant invoking a function version.
Data stored on local disk and in-memory Potentially accessible across all invocations of a function version. Potentially accessible across invocations from the same tenant. Not accessible for invocations from other tenants.
Cold starts Occur when there are no warm execution environments available to process incoming invocation. Occur when there are no tenant-specific warm execution environments available to process incoming invocation. More cold starts expected due to tenant-specific execution environments.

Integrating with Amazon API Gateway

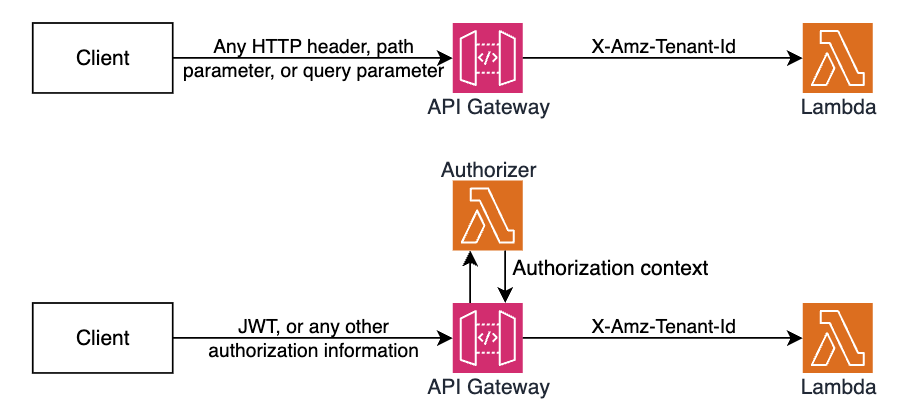
Amazon API Gateway uses Lambda’s Invoke API to invoke Lambda functions. When using the Invoke API, Lambda expects the tenant ID parameter to be passed using the X-Amz-Tenant-Id HTTP header. You can configure API Gateway to inject this HTTP header into the Lambda invocation request with a value obtained from client request properties such as HTTP header, query parameter, or path parameter. When using Lambda Authorizers, you can obtain the value from authorization context information returned by the authorizer, such as principal ID or JWT claim. See API Gateway documentation to learn how you can return authorization information from Lambda authorizers to be used for the X-Amz-Tenant-Id header value.

Figure 4. Obtaining X-Amz-Tenant-Id header value from authentication sources.

Figure 4. Obtaining X-Amz-Tenant-Id header value from authentication sources.

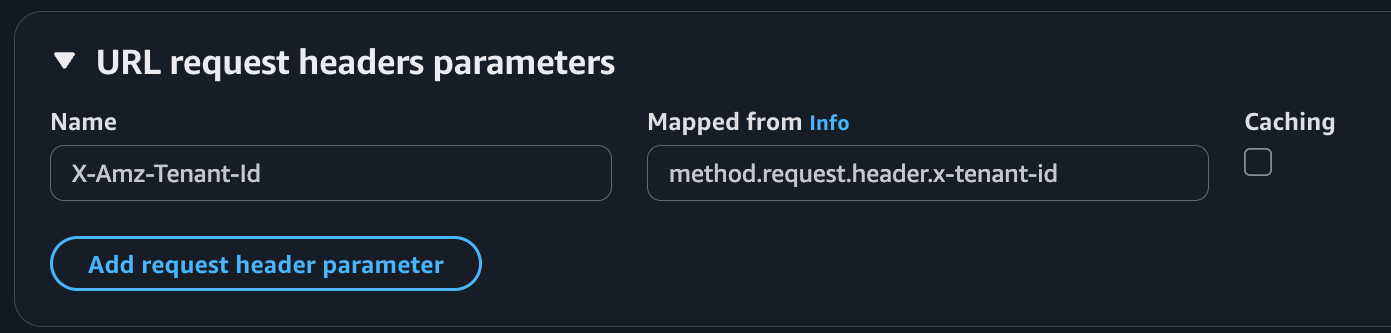
The following screenshot illustrates API Gateway Lambda integration configuration, where the incoming request to API Gateway includes an x-tenant-id header that is mapped to the X-Amz-Tenant-Id request header to invoke a Lambda function using tenant isolation mode.

Figure 5. Mapping client request header to Lambda tenant-id header.

Figure 5. Mapping client request header to Lambda tenant-id header.

The following code snippet illustrates this configuration implemented with the AWS CDK.

const lambdaIntegration = new ApiGw.LambdaIntegration(fn, {
   requestParameters: {
      // This configures API Gateway to inject X-Amz-Tenant-Id header
      // into downstream requests. The header value is obtained from 
      // x-tenant-id header in the client request.
      'integration.request.header.X-Amz-Tenant-Id': 'method.request.header.x-tenant-id'
   }
});

resource.addMethod('GET', lambdaIntegration, {
   requestParameters: {
      // This enables API Gateway to use the x-tenant-id header value 
      // obtained from the client request. The header name is arbitrary.
      // you can use any other header name. 
      'method.request.header.x-tenant-id': true
   }
});

Tenant-aware observability

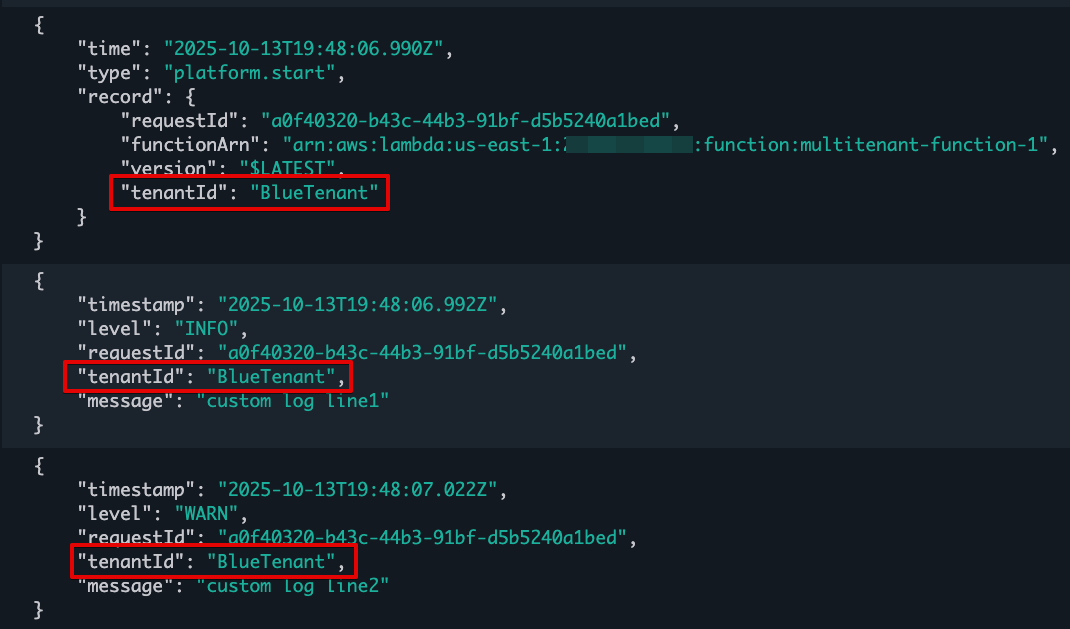
For functions using tenant isolation, Lambda automatically includes the tenant ID in function logs when you have JSON logging enabled, making it easier to monitor and debug tenant-specific issues. Note that the tenantId property is available during function invocation, rather than during function initialization. The tenantId property is included for both platform events (like platform.start and platform.report) and custom logs you print in your function code, as shown in the following screenshot:

Figure 6. Lambda function logs with tenantId.

Figure 6. Lambda function logs with tenantId.

Lambda creates a separate CloudWatch log stream for each execution environment. You can use CloudWatch Log Insights to find log streams that belong to a particular tenant by filtering by tenant Id:

fields @logStream, @message
| filter tenantId=='BlueTenant' or record.tenantId=='BlueTenant'
| stats count() as logCount by @logStream
| sort @timestamp desc

You can also retrieve tenant-specific logs across all log streams:

fields @message
| filter tenantId=='BlueTenant' or record.tenantId=='BlueTenant'
| limit 1000

Each log stream starts with function initialization logs followed by the invocation logs. This structure helps you to debug tenant-specific issues and understand the lifecycle of each tenant’s execution environments.

Considerations

When using the new tenant isolation for Lambda functions, consider the following:

  • Each tenant’s execution environments are isolated from other tenants so that tenant-specific data stored on disk or in memory remain separated from other tenants invoking the same Lambda function.
  • All tenants share the function’s execution role. For more fine-grained permissions for individual tenants, consider propagating tenant-scoped credentials from the upstream application components invoking your Lambda function.
  • Your application may experience higher percentage of cold starts, as Lambda processes requests in separate execution environments for each tenant invoking your functions.
  • You pay a fee for each new tenant-specific execution environment created, depending on the memory configured for your function. See Lambda pricing page for details.

Best practices

When using the new tenant isolation mode for Lambda functions, AWS recommends the following best practices:

  • Implement robust tenant ID validation at the application layer to prevent unauthorized access through tenant ID manipulation. Consider using a dedicated service or database to maintain valid tenant IDs.
  • Monitor and audit tenant access patterns regularly to detect potential security anomalies or unauthorized cross-tenant access attempts.
  • Be aware of Lambda concurrency quotas when building multi-tenant applications. You might need to request quota increases based on your tenant count and usage patterns.

Sample code

Follow the instructions in this GitHub repository to provision a sample project in your own account and see the new Lambda tenant isolation mode in action. The sample project illustrates how to integrate a function using the new tenant isolation mode with Amazon API Gateway and propagate tenant identity from client requests.

Conclusion

The new tenant isolation mode for Lambda simplifies building serverless multi-tenant SaaS applications on AWS. By automatically managing application tenant-level compute environment isolation, this capability eliminates the need for custom isolation logic or separate tenant functions, allowing you to focus on the core business logic while AWS handles the complexities of tenant-aware compute environment isolation.

Combined with the existing security features in Lambda, rapid scaling, and pay-per-use pricing, tenant isolation mode makes Lambda an even more compelling choice for modern SaaS applications, whether you’re building new solutions or enhancing existing ones.

To learn more, refer to the documentation for tenant isolation. For details on pricing, refer to Lambda’s pricing page.

How to update CRLs without public access using AWS Private CA

Post Syndicated from Rochak Karki original https://aws.amazon.com/blogs/security/how-to-update-crls-without-public-access-using-aws-private-ca/

Certificates and the hierarchy of trust they create are the backbone of a secure infrastructure. AWS Private Certificate Authority is a highly available certificate authority (CA) that you can use to create private CA hierarchies, secure your applications and devices with private certificates, and manage certificate lifecycles.

A certificate revocation list (CRL) is a file that contains a signed list of certificates revoked before their scheduled expiration date. Certificates can be revoked for a variety of reasons, including unintended key exposure, or because of discontinued use.

AWS Private CA writes CRLs to an Amazon Simple Storage Service (Amazon S3) bucket that you specify. CRLs are public, fully qualified domain names (FQDNs), but you might have requirements for a CRL that is only accessible internally to your organization, or you might have security standards that require all S3 buckets to have Amazon S3 block public access enabled.

The recommended practice for S3 buckets is to enable Block Public Access, which enables only authorized and authenticated AWS accounts to have access to a bucket and its contents. However, because some public key infrastructure (PKI) clients retrieve CRLs across the public internet, a workaround might be necessary to serve CRLs without requiring authenticated client access to an S3 bucket. One recommended solution is to use Amazon CloudFront to provide access to the CRL. This will likely be the best solution for most customers. Our documentation specifically highlights CloudFront as the recommended implementation path. However, you might not be able to use CloudFront or might need another option.

You might need a solution where the CRL lookups don’t traverse the public internet. In this post, we go over two different approaches to achieve this.

Option 1: Relocate CRLs to an internally accessible location

By default, AWS Private CA writes CRLs to an S3 bucket that you specify. This solution consists of moving the CRL to a separate location that is internally accessible to your TLS clients, but not accessible via the public internet such as an on-premises server. A CRL distribution point (CDP) is a link that points to the location of the CRL where revoked certificates appear. However, when private certificates are generated by AWS Certificate Manager (ACM), the CDP universal resource identifiers (URI) in the certificates point by default to the S3 bucket initially specified.

This solution uses a custom CNAME in the CDP to indicate, during certificate generation, the location where the CRL will ultimately be located.

The steps in the solution are as follows:

  1. Select the S3 bucket where the CRL will be stored.
  2. Issue a certificate through the CA with a custom CNAME.
  3. Create an AWS Lambda function that moves the CRL file from the S3 bucket to another specified location.
  4. Create an Amazon Simple Notification Service (Amazon SNS) notification that alerts a user to the success metric of the CRL generation event.

Prerequisites:

For this walkthrough, you must have the following resources ready to use:

  1. An AWS account with:
    • An AWS Identity and Access Management (IAM) role with permissions for Amazon S3, ACM Private CA, Amazon EventBridge, and Lambda
    • An ACM private CA root and subordinate CA configured in the same AWS Region
    • An S3 bucket for the CRL with permissions that allow the AWS Private CA service principal to PutObject, PutObjectACL, GetBucketACL and GetBucketLocation (see the following example bucket policy)
{     
    "Version": "2012-10-17",     
    "Statement": [         
        {             
            "Effect": "Allow",             
            "Principal": {                 
                "Service": "acm-pca.amazonaws.com"             
            },             
            "Action": [                 
                "s3:PutObject",                 
                "s3:PutObjectAcl",                 
                "s3:GetBucketAcl",                 
                "s3:GetBucketLocation"             
            ],             
            "Resource": [                 
                "arn:aws:s3:::<name-of-bucket>/*",                 
                "arn:aws:s3:::<name-of-bucket>"             
            ],             
            "Condition": {                 
                "StringEquals": {                     
                    "aws:SourceAccount": "<account-num-here>",                     
                    "aws:SourceArn": "<subordinate-ca-arn-here>"                 
                }             
            }         
        }     
    ] 
}

2. AWS Command Line Interface (AWS CLI) configured

Deploy:

With the prerequisites in place, you’re ready to deploy the first solution.

To enable CRL distribution:

  1. Use your account to sign in to the AWS Management Console for AWS Private Certificate Authority.
  2. Select the name of your subordinate CA. This should take you to another page with more details.
  3. Scroll down and choose the Revocation configuration tab.
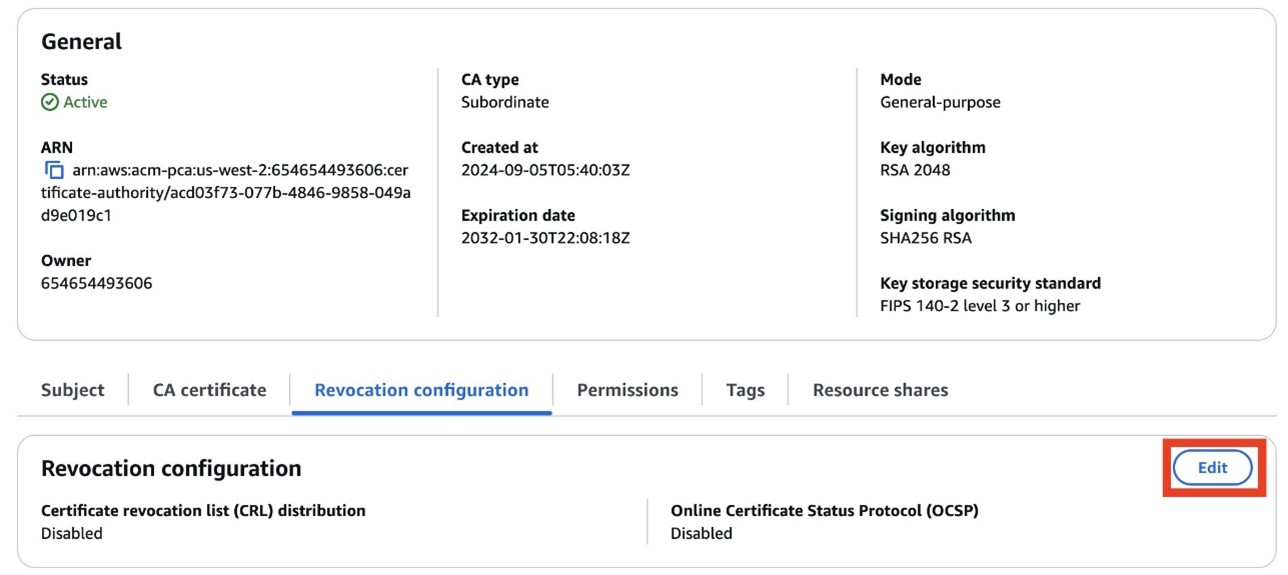
  4. Choose Edit on the top right.
  5. Figure 1: Edit the revocation configuration

    Figure 1: Edit the revocation configuration

  6. Select Activate CRL distribution. Select the CRL S3 bucket you created prior to the walkthrough.
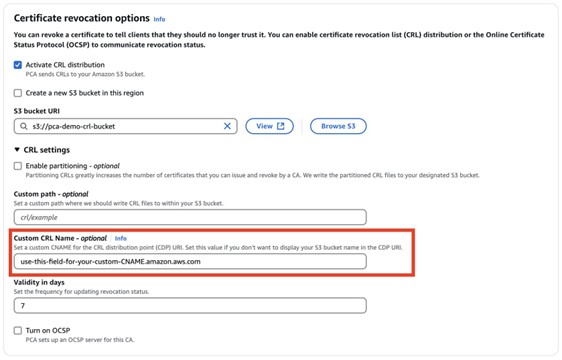
  7. Figure 2: Enter a name for your CRL

    Figure 2: Enter a name for your CRL

  8. Modify the CDP by expanding the CRL settings dropdown. In the Custom CRL Name field, enter the URL where you will eventually move the CRL. This should be a place that is accessible by your internal organization, but not accessible externally. If you use partitioned CRLs, select the Enable partitioning checkbox. To learn more about CRL partitioning, see Plan your AWS Private CA certificate revocation method.
  9. Choose Save changes.

To create an SNS topic and Lambda function:

  1. Go to the Amazon SNS console.
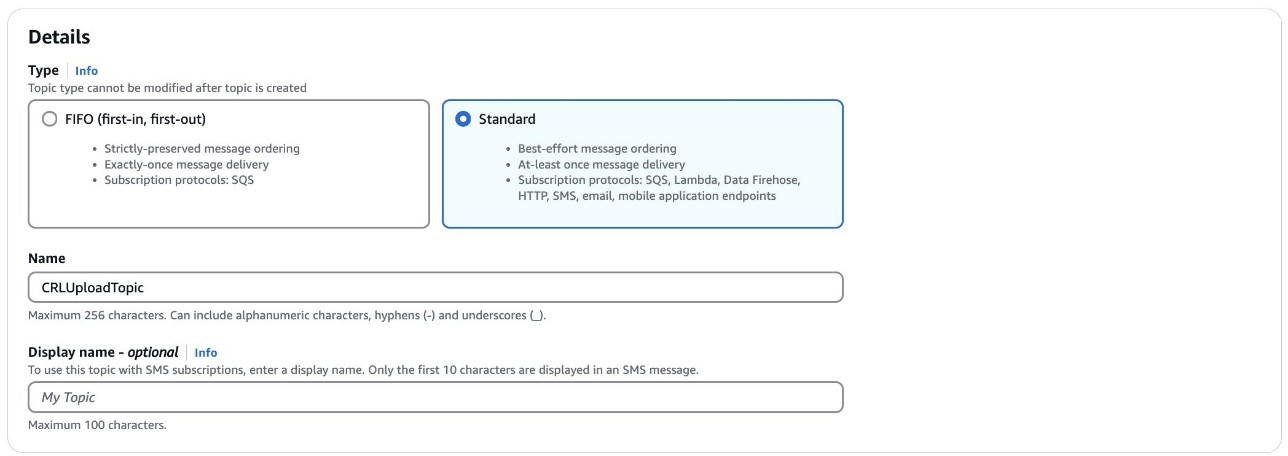
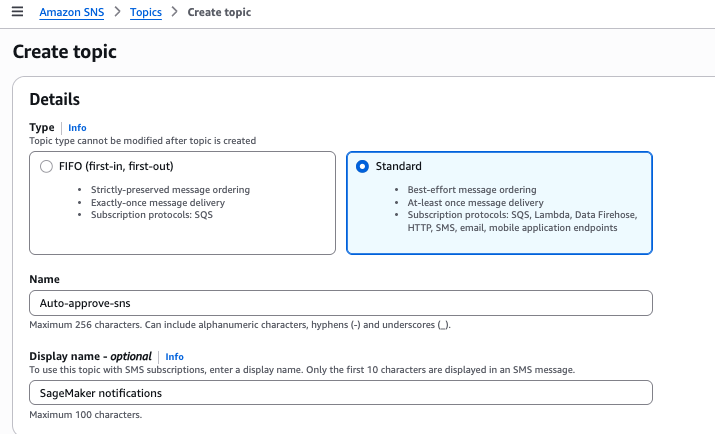
  2. Create a standard SNS topic. Leave all options as default and subscribe an appropriate email to the topic.
  3. Figure 3: Create an SNS topic

    Figure 3: Create an SNS topic

  4. Go to the Lambda console.
  5. Choose Create Function.
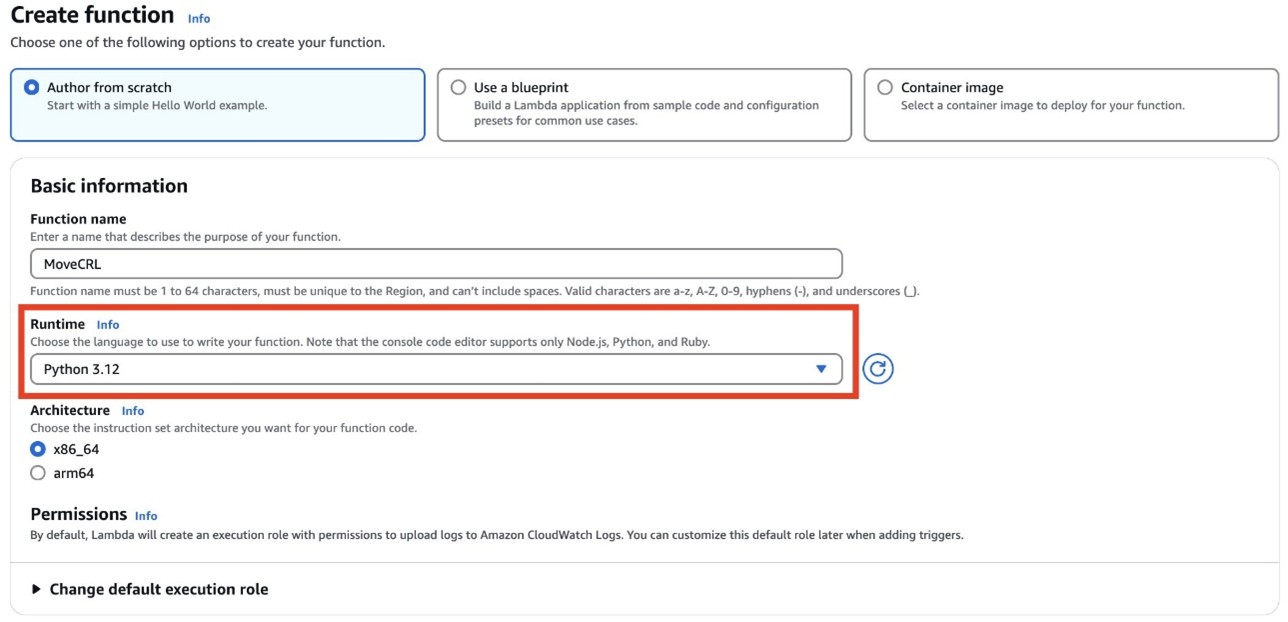
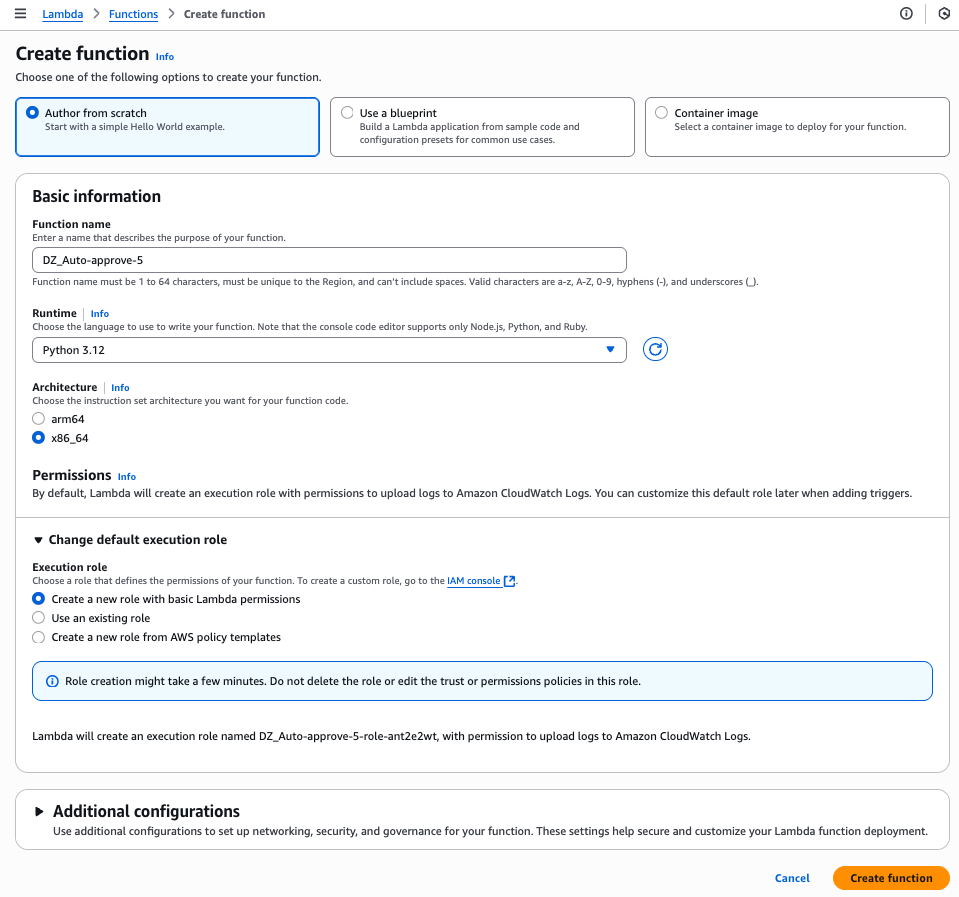
  6. Enter a name for your function. Under Runtime, select Python 3.12 from the dropdown.
  7. Figure 4: Create a Lambda function

    Figure 4: Create a Lambda function

  8. Verify that the role associated with your Lambda function has permissions to get objects from the S3 bucket where AWS Private CA places the CRL (set when you configured the revocation details for the CA), copy objects in Amazon S3, then put objects in an S3 bucket (or wherever the new CRL distribution point specified in the certificate custom CNAME will be—for example, an internal-only accessible location), and publish to an Amazon SNS topic. The Lambda function also checks the success metric of a CRL generation event. If the event fails, an SNS topic will notify an admin. If the event is successful, a copy of the CRL in the original S3 bucket is created in the new specified location and an SNS topic will notify an admin.

Example code (Python 3.13):

import boto3 
import json 

def lambda_handler(event, context):     
	#create a s3 client     
	s3 = boto3.client('s3')          

	#create a sns client     
	sns = boto3.client('sns')     
    topicArn = "<sns-topic-arn-here>”     
    
    #get name of the CA from the CW event     
    caID = event['resources'][0].split('/')[-1]          
    status = event['detail']['result']     
    if status == 'success':              
    	
        source = '<ORIGINS3BUCKET>'         
        destination = '<DESTINATION-S3BUCKET>'         
        #See below note for more clarification on S3 CRL paths         
        folder = 'crl/'         
        file = caID + '.crl'         
        key = folder + file              
        
        try:             
        	copySource = {                 
            	'Bucket': source,                 
                'Key': key             
           	}                      
            
            s3.copy_object(                 
            	CopySource=copySource,                 
                Bucket=destination,                 
                Key=file             
          	)             
            response = sns.publish(                 
            	TopicArn=<sns-topicArn>,                 
                Message=f'Successfully moved {key} from {source} to {destination} in {caID}',                 
                Subject="CRL Upload Success"             
          	)                      
            
            return {                 
            	'statusCode': 200,                 
                'body': json.dumps(f'Successfully moved {key} from {source} to {destination} in {caID}')             
          	}                  
    	
        except s3.exceptions.NoSuchKey:             
        	response = sns.publish(                 
            	TopicArn=<sns-topicArn>,                 
                Message=f"Object {key} not found in {source}",                 
                Subject='CRL Upload Failure'             
          	)             
            return {                 
            	'statusCode': 404,                 
                'body': json.dumps(f'Object {key} not found in {source}')             
          	}                  
   		except Exception as e:             
    		print(e)             
        	response = sns.publish(                 
        		TopicArn=<sns-topicArn>,                 
            	Message=f'Error moving object: {str(e)}',                 
            	Subject='Failure Uploading CRL'             
     		)             
			return {                 
    			'statusCode': 500,                 
        		'body': json.dumps(f'Error moving object: {str(e)}')             
  			}     
    else:         
    	response = sns.publish(                 
        		TopicArn=<sns-topicArn>,                 
            	Message=f'Certificate Authority {caID} CRL creation {status}',                 
            	Subject='CRL Upload Failure'             
     		)         
        return {             
        	'statusCode': 200,             
            'body': json.dumps(f'Certificate Authority {caID} CRL creation {status}')         
      	}

Note: By default, the non-partitioned CRL path in S3 is <s3-bucket-name>/crl/<CA-ID>.crl. If you used a custom path, modify the path name to the CRL accordingly. Alternatively, if using partitioned CRLs, the path changes to <s3-bucket-name>/crl/<CA-ID>/<partition_GUID>.crl; in that case, you can loop over each file in the <CA-ID> path to achieve the same effect.

To create an EventBridge that deploys your Lambda function:

  1. Go to the EventBridge console. Under Buses, select Rules.
  2. Choose Create Rule.
  3. Enter a name for your rule. Under Rule Type, select Rule with an Event Pattern and choose Next.
  4. Under Events, select AWS events or EventBridge partner events as the Event Source.
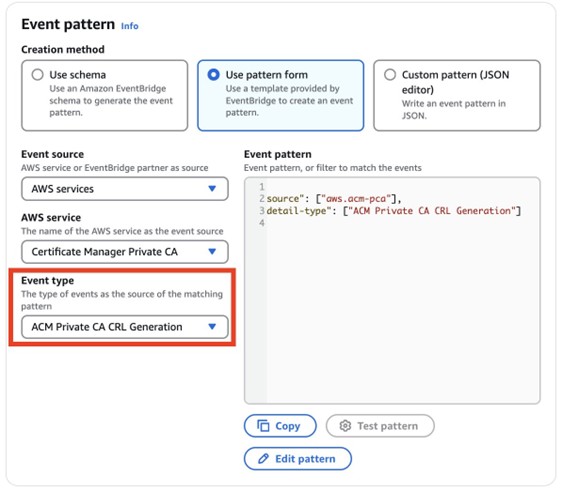
  5. For the Event pattern, select Use pattern form. For the Event source, select AWS services. For Event Type, select ACM Private CA CRL Generation.
Figure 5: Configure the event pattern

Figure 5: Configure the event pattern

  1. Choose Next.
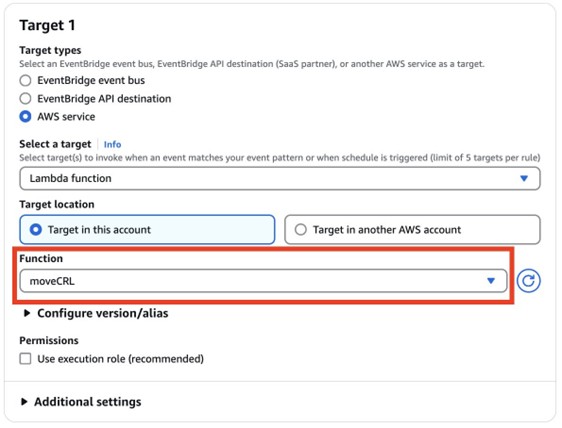
  2. Under Target types, choose AWS Service, and then select Lambda function from the Select a target dropdown and select the function that you created earlier.
  3. Figure 6: Select the Lambda function as the target

    Figure 6: Select the Lambda function as the target

  4. Choose Next. Review your topic, then choose Update rule.
  5. To test the success of the Lambda function:

    1. To test the EventBridge topic, create and revoke a certificate. You can do this using the AWS CLI by getting the serial number of a certificate using openSSL:
      openssl x509 -in cert.pem -noout -serial
    2. Use the following command to revoke the certificate:
      aws acm-pca revoke-certificate —certificate-authority-arn <CA ARN> \ —certificate-serial <SERIAL NUMBER RETURNED IN STEP 1> --revocation-reason “UNSPECIFIED”
    3. To make sure that the Lambda function is triggered, wait 5–30 minutes. Check CloudTrail to make sure that RevokeCertificate was called, then monitor the CloudWatch log of the Lambda function. You should also get a notification message from your SNS topic.
    4. You have now successfully moved your CRL to a new location.

    Option 2: Implement Private CRL Access Through AWS Private CA

    This solution provides private Certificate CRL access within AWS Private CA, avoiding the need for public internet exposure. The design centers on establishing root and subordinate CAs with CRL functionality enabled within a dedicated S3 bucket, combined with a private network infrastructure using Gateway VPC endpoints and private subnets. Security is enforced through an S3 bucket policy that accomplishes three critical objectives:

    • Authorizing essential AWS Private CA permissions
    • Constraining CRL access to a designated Gateway VPC endpoint
    • Explicitly blocking access attempts from other sources.

    The solution includes private DNS zone configuration for proper resolution and can be verified through access testing confirming successful CRL retrieval from private VPC instances while making sure that requests from public instances are denied, maintaining a strictly private PKI.

    1. Create a root CA and subordinate CA with CRL enabled
    2. Configure a dedicated S3 bucket for CRL storage
    3. Issue private certificates through ACM
    4. Set up a VPC with private subnets
    5. Configure a Gateway VPC endpoint for Amazon S3
    6. Set up route tables for local traffic only
    7. Implement an S3 bucket policy with specific permissions
    8. Configure private DNS resolution
    9. Set up access controls through VPC endpoints
    10. Test private access from within the VPC
    11. Verify that public access is blocked

    Prerequisites for CRL solution 2

    For this walkthrough, you must have the following resources available:

    Deploy CRL solution 2

    With the prerequisites in place, you’re ready to use the console and AWS CLI to deploy the solution.

    To deploy the solution:

    1. Go to the AWS Private Certificate Authority console.
    2. In the navigation pane, choose Create a Private CA.
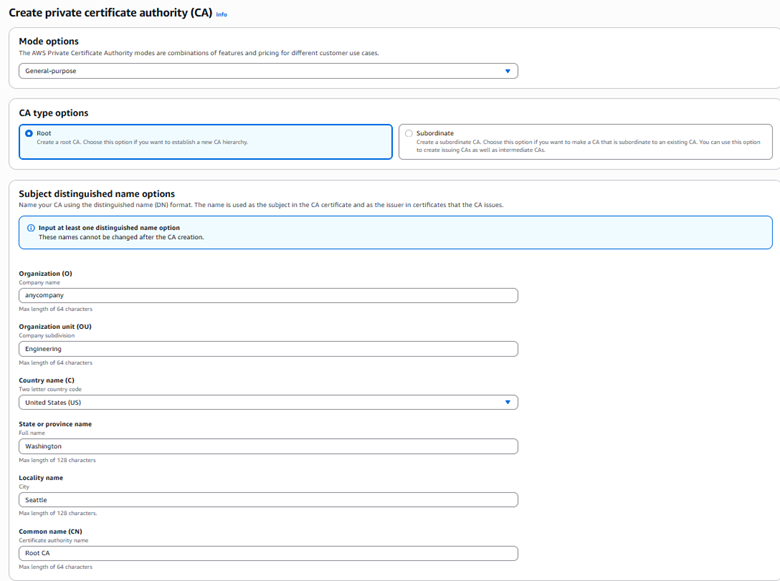
      1. Under Mode options, select General-purpose.
      2. For CA type options, select root.
      3. For the Subject distinguished name options: Fill in at least one of the subject distinguished name options: Organization(O), Organization unit (OU), Country(C), State, Locality name, and Common name (CN).
        Figure 7: Create a private CA (root)

        Figure 7: Create a private CA (root)

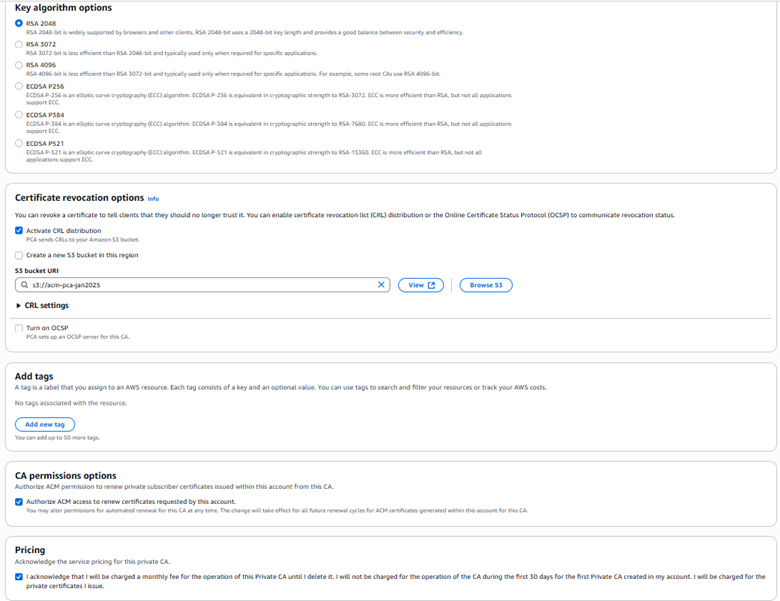
      4. Select Key algorithm options, for example, RSA 2046.
      5. Under Certificate revocation options, select Activate CRL Distribution, and select or create an S3 bucket for CRL storage.
      6. Under Pricing, select the checkbox to acknowledge pricing and then select Create CA.
    Figure 8: Configure a private CA (root)

    Figure 8: Configure a private CA (root)

    3. After creating a root CA, repeat all of step 2 to create a subordinate CA, selecting
    Subordinate CA under
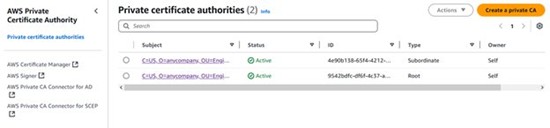
    CA options (step 2-b). When completed, both the root CA and subordinate CA will be visible on the Private certificate authority page.

    Figure 9: View of root CA and subordinate CA

    Figure 9: View of root CA and subordinate CA

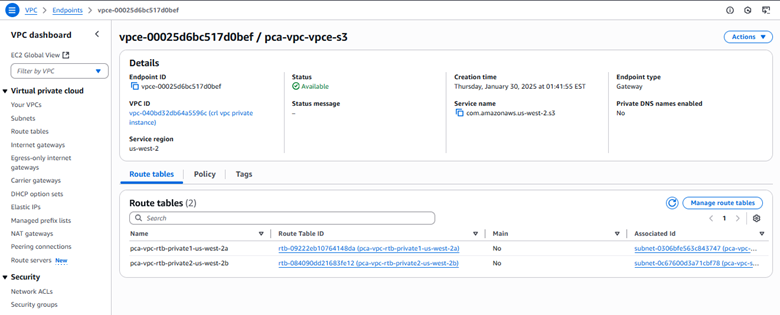
    With the root CA and subordinate CA in place, the next step is to create a VPC gateway endpoint for S3 access to enable private network communication.

    To create a VPC gateway endpoint:

    1. Go to the Amazon VPC console
    2. In the left navigation pane, select Endpoints, and choose Create Endpoint.
    3. Configure the Gateway VPC endpoint settings:
      1. Enter a descriptive name for your endpoint (optional).
      2. Type: Select AWS services.
      3. Services: Select the service name com.amazonaws.[region].s3 from the list.
      4. Type: Verify that Gateway is selected (automatically chosen for Amazon S3).
      5. VPC: Choose the VPC where you want to create the endpoint.
      6. Route tables: Select the route tables associated with the subnets that need Amazon S3 access.
      7. Policy: Select Full Access or create a custom policy to restrict access to specific S3 buckets or actions.
      8. Review your configuration and choose Create endpoint.
    Figure 10: Gateway VPC endpoint configuration

    Figure 10: Gateway VPC endpoint configuration

    1. Create two private subnets:
      1. In the Amazon VPC console, choose Subnets and then Create subnet.
      2. Select your VPC and enter the subnet details (name, Availability Zone, and CIDR block).
      3. Repeat for the second subnet in a different Availability Zone.
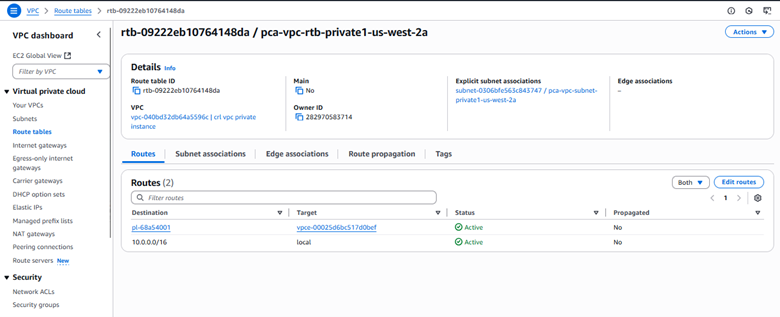
    2. Configure route tables:
      1. Navigate to Route Tables and choose Create route table.
      2. Create and name two route tables for your private subnets.
      3. Associate each route table with its corresponding private subnet.
      4. Make sure that each route table contains only local routes (VPC CIDR).
      5. Remove any routes for internet access (0.0.0.0/0).
    Figure 11: Private route table configuration

    Figure 11: Private route table configuration

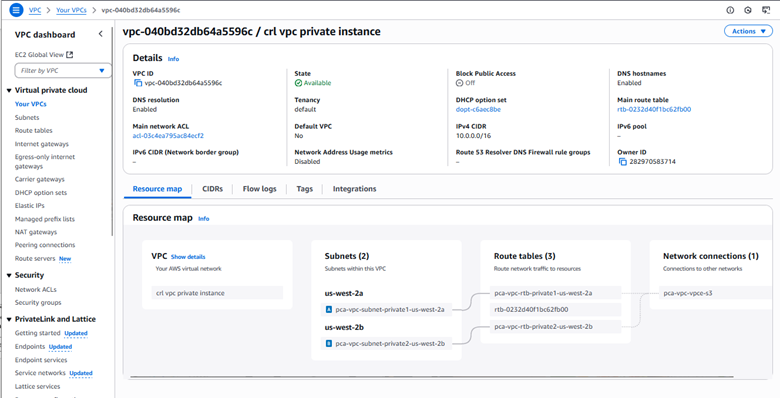
    1. You can see now see under Resource Map that the Gateway VPC endpoint provides secure access to Amazon S3 resources within the private network.
    Figure 12: VPC private instance configuration

    Figure 12: VPC private instance configuration

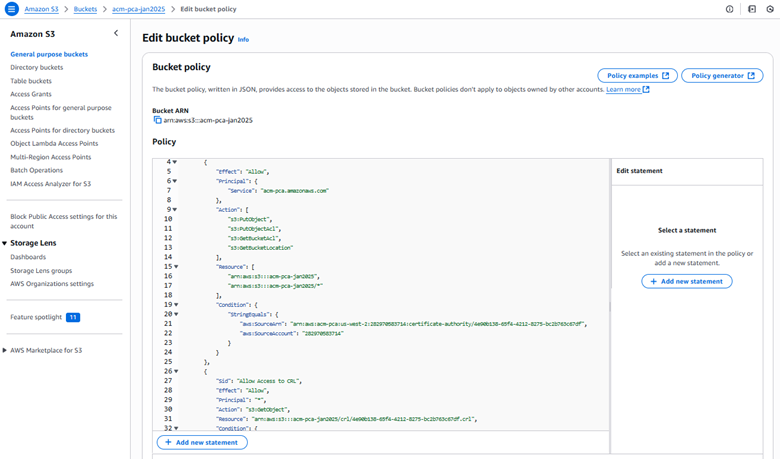
    1. Use the following example code to implement a bucket policy that enforces the following key security controls:
      • Grant AWS Private CA the necessary permissions for certificate management.
      • Restrict CRL access exclusively through the specified VPC endpoint.
      • Explicitly deny GetObject requests not originating from the designated Gateway VPC endpoint.
    Figure 13: S3 bucket policy

    Figure 13: S3 bucket policy

    The following is an example S3 bucket policy for private CA CRL access with VPC endpoint restrictions:

    {     
        "Version": "2012-10-17",     
        "Statement": [         
            {             
                "Effect": "Allow",             
                "Principal": {                 
                    "Service": "acm-pca.amazonaws.com"             
                    },             
                "Action": [                 
                    "s3:PutObject",                 
                    "s3:PutObjectAcl",                 
                    "s3:GetBucketAcl",                 
                    "s3:GetBucketLocation"             
                ],             
                "Resource": [                 
                    "<arn:aws:s3:::BUCKET_NAME>",                 
                    "<arn:aws:s3:::BUCKET_NAME>/"           
                ],           
                "Condition": {               
                    "StringEquals": {                   
                        "aws:SourceArn": "<arn:aws:acm-pca:REGION:ACCOUNT_ID:certificate-authority/CA_ID>",                   
                        "aws:SourceAccount": "<ACCOUNT_ID>"               
                        }           
                }       
            },       
            {           
                "Sid": "Allow Access to CRL",           
                "Effect": "Allow",            
                "Principal": "",             
                "Action": "s3:GetObject",             
                "Resource": "<arn:aws:s3:::BUCKET_NAME/crl/CA_ID.crl>",             
                "Condition": {                 
                    "StringEquals": {                     
                        "aws:SourceVpce": "<VPCE_ID>"                 
                        }             
                }         
            },         
            {             
                "Sid": "Access-to-specific-VPCE-only",             
                "Effect": "Deny",             
                "Principal": "",            
                "Action": "s3:GetObject",           
                "Resource": [               
                    "<arn:aws:s3:::BUCKET_NAME>",               
                    "<arn:aws:s3:::BUCKET_NAME>/"             
                ],             
                "Condition": {                 
                    "StringNotEquals": {                     
                        "aws:SourceVpce": "<VPCE_ID>"                 
                        }             
                }         
            }     
        ] 
    }

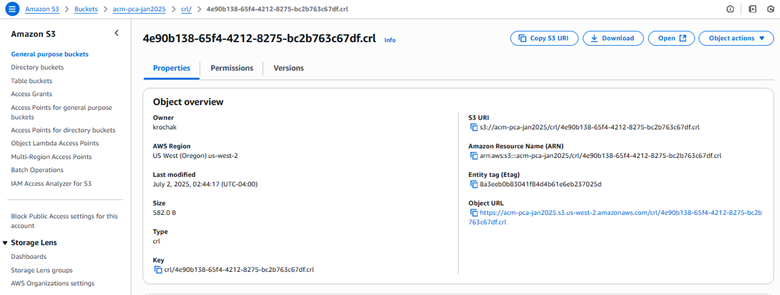
    Figure 14: S3 bucket CRL properties

    Figure 14: S3 bucket CRL properties

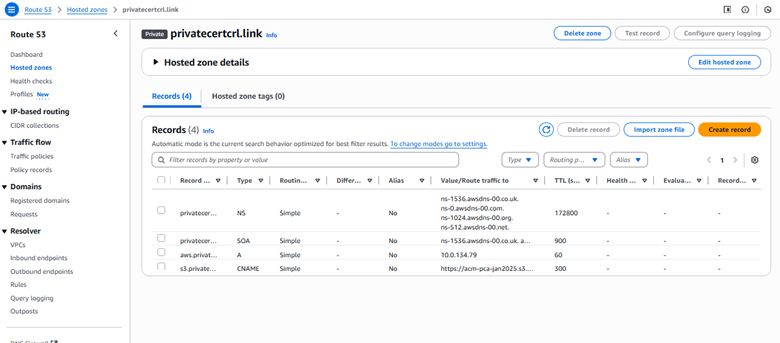
    Create a private hosted zone:

    1. Go to the Route 53 console.
    2. In the left navigation pane, choose Hosted zones.
    3. Choose Create hosted zone.
    4. Configure the following:
      1. Domain name: Enter s3.amazonaws.com
      2. Description: (optional) enter Private hosted zone for S3 CRL endpoint
      3. Type: Select Private hosted zone.
      4. VPC: For Region, select your VPC’s Region; for VPC ID, select your VPC from the dropdown list.
    5. Choose Create hosted zone.

    Create a record set:

    1. Inside your new private hosted zone:
      1. Choose Create record.
      2. Select Simple routing policy.
      3. Choose Next.
    2. Configure record:
      1. Record name: Enter your S3 bucket name.
      2. Record type: Select A – Routes traffic to an IPv4 address.
      3. Alias: Toggle Yes.
      4. Route traffic to: Select Alias to S3 website endpoint.
      5. Region: Select your Region.
      6. S3 endpoint: Select from dropdown list.
      7. TTL: Leave as default (300 seconds).
    3. Choose Create record.
    Figure 15: Hosted zone details

    Figure 15: Hosted zone details

    Verify configuration:

    1. Go to the Amazon EC2 console and choose Launch instance.
    2. Select Amazon Linux 2.
    3. Choose Instance Type.
    4. Select you VPC and subnet.
    5. Under Network settings, select Create security group, then choose Allow SSH traffic from and enter your IP address.
    6. Choose Launch instance.
    7. After the instance is launched, select the instance and choose Connect.
    8. Select EC2 Instance Connect and choose Connect.

    Test the solution

    To test private access from an EC2 instance within your private VPC, verify CRL access using:
    curl -s https://<bucket-name>.s3.<region>.amazonaws.com/crl/<certificate-id>.crl | openssl crl -text -noout

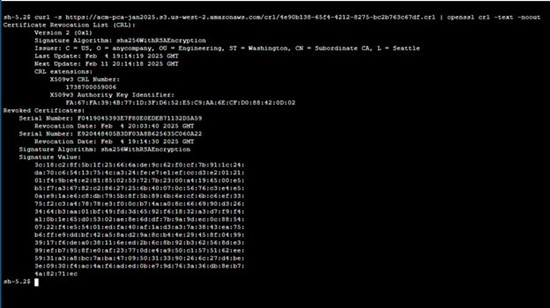
    If successful, the command completes the following steps, as shown in Figure 16:

    1. Retrieves the CRL from Amazon S3
    2. Decodes it using OpenSSL
    3. Displays comprehensive CRL information including issuer details, update timestamps, revoked certificate list, signature algorithm, and other metadata
    Figure 16: Public access verification

    Figure 16: Public access verification

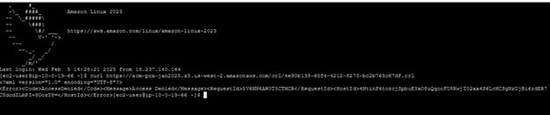
    To validate your security controls, attempt access from a public EC2 instance using the following command:
    curl https://<bucket-name>.s3.<region>.amazonaws.com/crl/<certificate-id>.crl

    This should fail, receiving an access denied error confirming that the CRL cannot be accessed from the public internet, as shown in Figure 17.

    Figure 17: Access denied error confirming that the CRL cannot be accessed from the public internet

    Figure 17: Access denied error confirming that the CRL cannot be accessed from the public internet

    Conclusion

    In this post, we walked you through two solutions that you can use to make your CRLs accessible to your internal organization, but not publicly available. First, we showed you how to configure a custom CNAME in your CRL distribution point and deploy Lambda functions to automatically copy each newly generated CRL from the default S3 bucket into a private S3 store.

    Next, we showed you a VPC architecture that uses an Amazon S3 VPC gateway endpoint, tightly scoped bucket policies, and private Route 53 DNS zones to make sure that CRL retrieval is confined to your VPC. We also covered the essential IAM and bucket policies that your clients need to access those CRLs securely. You can get started with setting up this solution on AWS Private CA today.

    If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Certificate Manager forum or contact AWS Support.

Rochak Karki

Rochak Karki

Rochak is a Security Specialist Solutions Architect at AWS, focusing on threat detection, incident response, and data protection helping customers build secure environments. Rochak is a US Army veteran and holds a Bachelor of Science in Engineering from the University of Wyoming. Outside of work, he enjoys spending time with family and friends, hiking, and traveling.

Cheryl Wang

Cheryl is an Associate Security Solutions Architect at AWS based in the SF Bay Area. Cheryl is passionate about cybersecurity and helping customers improve their security infrastructure. She holds a B.A. in Computer Science from Wellesley College. Outside of work, she enjoys writing and playing guzheng.

Getting started with Amazon S3 Tables in Amazon SageMaker Unified Studio

Post Syndicated from David Pasha original https://aws.amazon.com/blogs/big-data/getting-started-with-amazon-s3-tables-in-amazon-sagemaker-unified-studio/

Modern data teams face a critical challenge: their analytical datasets are scattered across multiple storage systems and formats, creating operational complexity that slows down insights and hampers collaboration. Data scientists waste valuable time navigating between different tools to access data stored in various locations, while data engineers struggle to maintain consistent performance and governance across disparate storage solutions. Teams often find themselves locked into specific query engines or analytics tools based on where their data resides, limiting their ability to choose the best tool for each analytical task.

Amazon SageMaker Unified Studio addresses this fragmentation by providing a single environment where teams can access and analyze organizational data using AWS analytics and AI/ML services. The new Amazon S3 Tables integration solves a fundamental problem: it enables teams to store their data in a unified, high-performance table format while maintaining the flexibility to query that same data seamlessly across multiple analytics engines—whether through JupyterLab notebooks, Amazon Redshift, Amazon Athena, or other integrated services. This eliminates the need to duplicate data or compromise on tool choice, allowing teams to focus on generating insights rather than managing data infrastructure complexity.

Table buckets are the third type of S3 bucket, taking place alongside the existing general purpose buckets, directory buckets, and now the fourth type – vector buckets. You can think of a table bucket as an analytics warehouse that can store Apache Iceberg tables with various schemas. Additionally, S3 Tables deliver the same durability, availability, scalability, and performance characteristics as S3 itself, and automatically optimize your storage to maximize query performance and to minimize cost.

In this post, you learn how to integrate SageMaker Unified Studio with S3 tables and query your data using Athena, Redshift, or Apache Spark in EMR and Glue.

Integrating S3 Tables with AWS analytics services

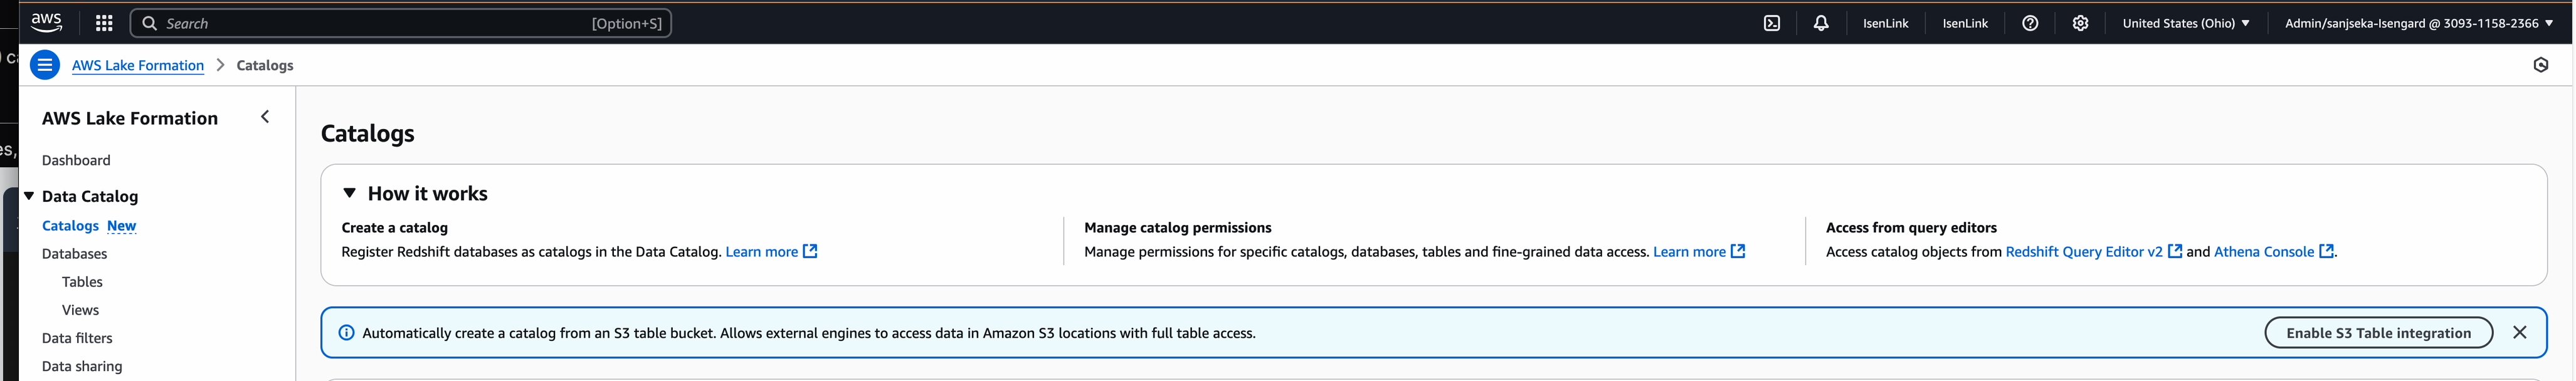
S3 table buckets integrate with AWS Glue Data Catalog and AWS Lake Formation to allow AWS analytics services to automatically discover and access your table data. For more information, see creating an S3 Tables catalog.

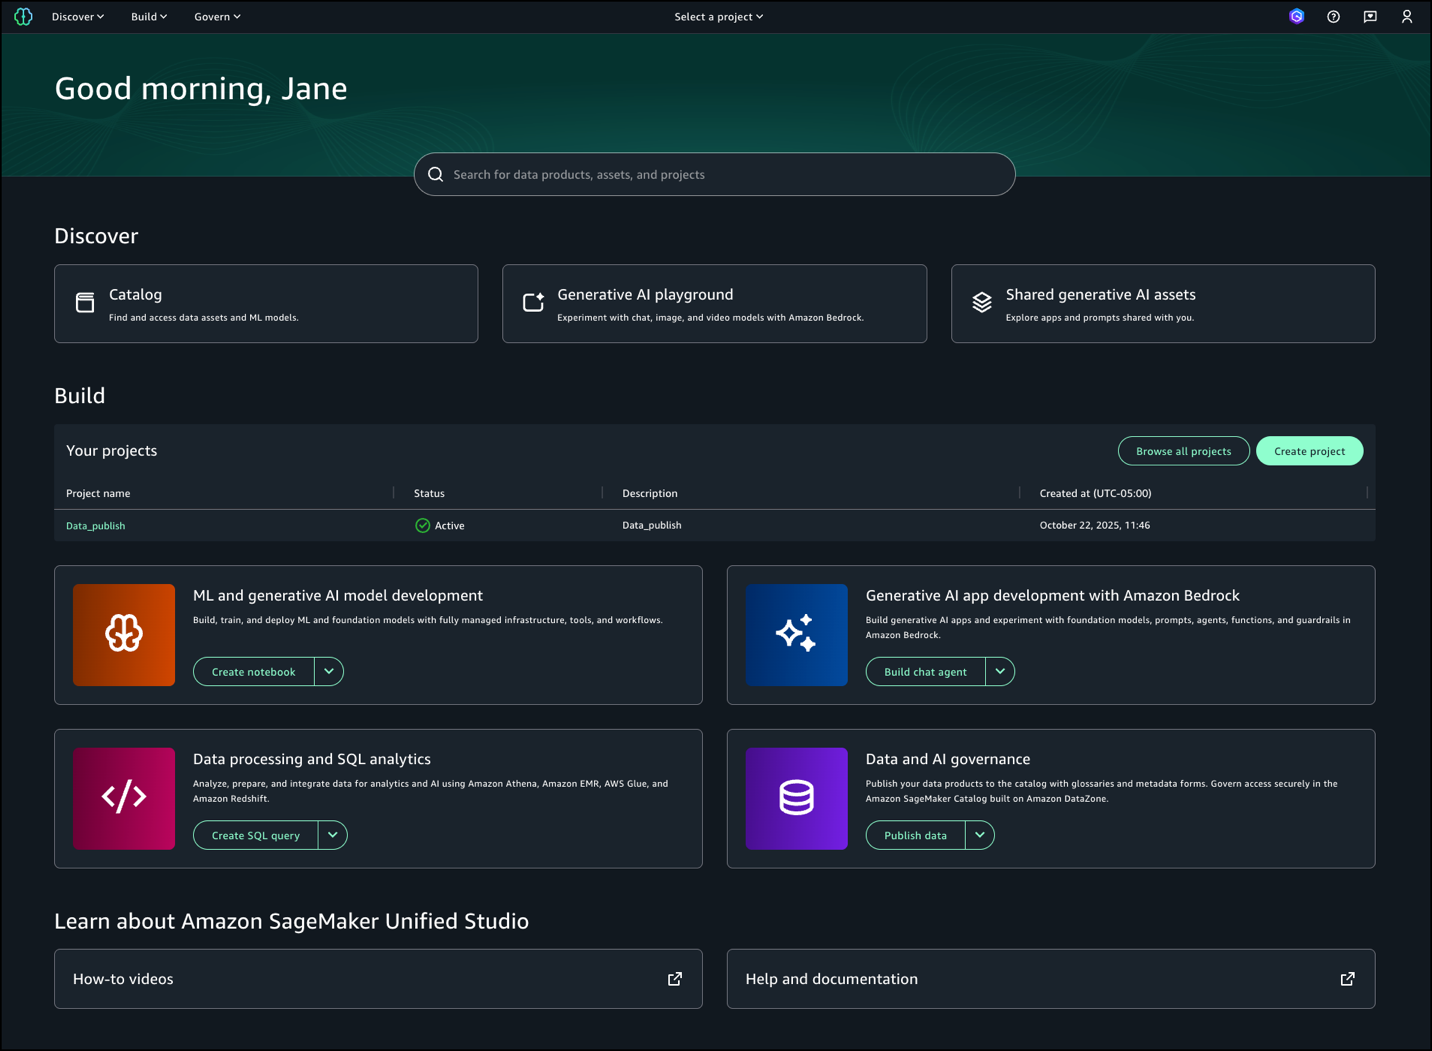
Before you get started with SageMaker Unified Studio, your administrator must first create a domain in the SageMaker Unified Studio and provide you with the URL. For more information, see the SageMaker Unified Studio Administrator Guide.

If you’ve never used S3 Tables in SageMaker Studio, you can allow it to enable the S3 Tables analytics integration when you create a new S3 Tables catalog in SageMaker Unified Studio.

Note: This integration needs to be configured individually in each AWS Region.

When you integrate using SageMaker Unified Studio, it takes the following actions in your account:

  • Creates a new AWS Identity and Access Management (IAM) service role that gives AWS Lake Formation access to all your tables and table buckets in the same AWS Region where you are going to provision the resources. This allows Lake Formation to manage access, permissions, and governance for all current and future table buckets.
  • Creates a catalog from an S3 table bucket in the AWS Glue Data Catalog.
  • Add the Redshift service role (AWSServiceRoleForRedshift) as a Lake Formation Read-only administrator permissions.

Prerequisites

Creating catalogs from S3 table buckets in SageMaker Unified Studio

To get started using S3 Tables in SageMaker Unified Studio you create a new Lakehouse catalog with S3 table bucket source using the following steps.

  1. Open the SageMaker console and use the region selector in the top navigation bar to choose the appropriate AWS Region.
  2. Select your SageMaker domain.
  3. Select or create a new project you want to create a table bucket in.
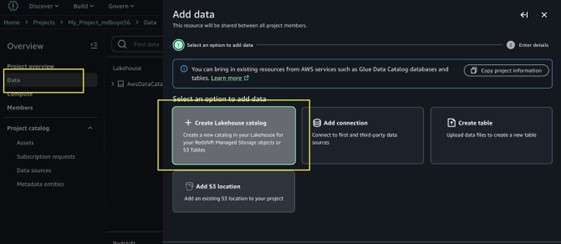
  4. In the navigation menu select Data, then select + to add a new data source.
  5. Choose Create Lakehouse catalog.
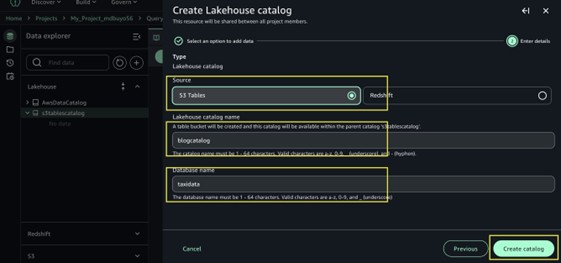
  6. In the add catalog menu, choose S3 Tables as the source.
  7. Enter a name for the catalog blogcatalog.
  8. Enter database name taxidata.
  9. Choose Create catalog.
  10. The following steps will help you create these resources in your AWS account:
    1. A new S3 table bucket and the corresponding Glue child catalog under the parent Catalog s3tablescatalog.
    2. Go to Glue console, expand Data Catalog, Click databases, a new database within that Glue child catalog. The database name will match the database name you provided.
    3. Wait for the catalog provisioning to finish.
  11. Create tables in your database, then use the Query Editor or a Jupyter notebook to run queries against them.

Creating and querying S3 table buckets

After adding an S3 Tables catalog, it can be queried using the format s3tablescatalog/blogcatalog. You can begin creating tables within the catalog and query them in SageMaker Studio using the Query Editor or JupyterLab. For more information, see Querying S3 Tables in SageMaker Studio.

Note: In SageMaker Unified Studio, you can create S3 tables only using the Athena engine. However, once the tables are created, they can be queried using Athena, Redshift, or through Spark in EMR and Glue.

Using the query editor

Creating a table in the query editor

  1. Navigate to the project you created in the top center menu of the SageMaker Unified Studio home page.
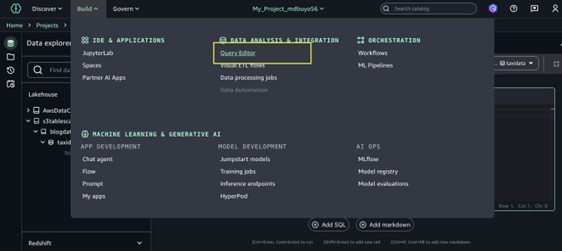
  2. Expand the Build menu in the top navigation bar, then choose Query editor.
  3. Launch a new Query Editor tab. This tool functions as a SQL notebook, enabling you to query across multiple engines and build visual data analytics solutions.
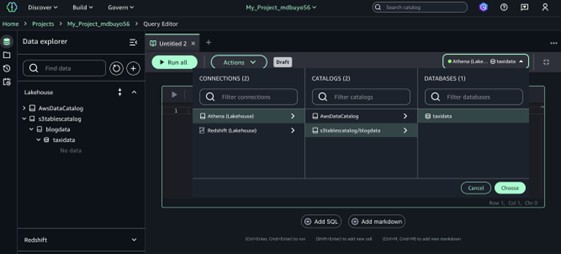
  4. Select a data source for your queries by using the menu in the upper-right corner of the Query Editor.
    1. Under Connections, choose Lakehouse (Athena) to connect to your Lakehouse resources.
    2. Under Catalogs, choose S3tablescatalog/blogcatalog.
    3. Under Databases, choose the name of the database for your S3 tables.
  5. Select Choose to connect to the database and query engine.
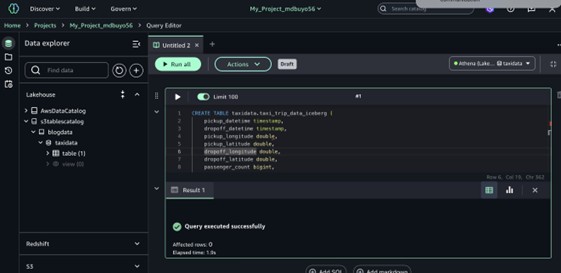
  6. Run the following SQL query to create a new table in the catalog.
    CREATE TABLE taxidata.taxi_trip_data_iceberg (
    pickup_datetime timestamp,
    dropoff_datetime timestamp,
    pickup_longitude double,
    pickup_latitude double,
    dropoff_longitude double,
    dropoff_latitude double,
    passenger_count bigint,
    fare_amount double
    )
    PARTITIONED BY
    (day(pickup_datetime))
    TBLPROPERTIES (
    'table_type' = 'iceberg'
    );

    After you create the table, you can browse to it in the Data explorer by choosing S3tablescatalog →s3tableCatalog →taxidata→taxi_trip_data_iceberg.

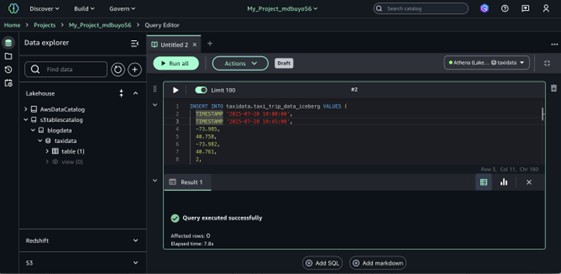
  7. Insert data into a table with the following DML statement.
    INSERT INTO taxidata.taxi_trip_data_iceberg VALUES (
    TIMESTAMP '2025-07-20 10:00:00',
    TIMESTAMP '2025-07-20 10:45:00',
    -73.985,
    40.758,
    -73.982,
    40.761,
    2, 23.75
    );

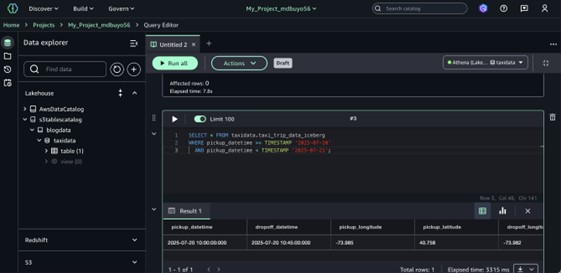
  8. Select data from a table with the following query.
    SELECT * FROM taxidata.taxi_trip_data_iceberg
    WHERE pickup_datetime >= TIMESTAMP '2025-07-20'
    AND pickup_datetime < TIMESTAMP '2025-07-21';

You can learn more about the Query Editor and explore additional SQL examples in the SageMaker Unified Studio documentation.

Before proceeding with JupyterLab setup:

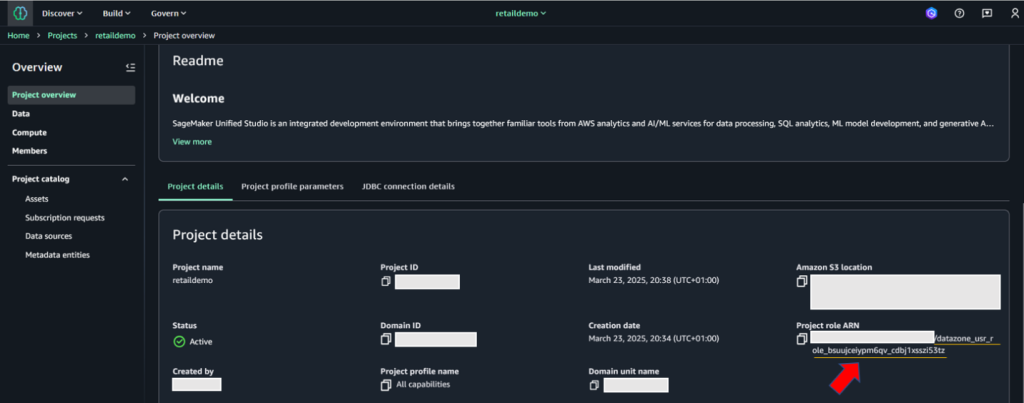
To create tables using the Spark engine via a Spark connection, you must grant the S3TableFullAccess permission to the Project Role ARN.

  1. Locate the Project Role ARN in SageMaker Unified Studio Project Overview.
  2. Go to the IAM console then select Roles.
  3. Search for and select the Project Role.
  4. Attach the S3TableFullAccess policy to the role, so that the project has full access to interact with S3 Tables.

Using JupyterLab

  1. Navigate to the project you created in the top center menu of the SageMaker Unified Studio home page.
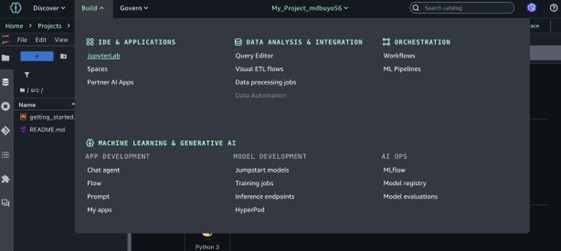
  2. Expand the Build menu in the top navigation bar, then choose JupyterLab.
  3. Create a new notebook.
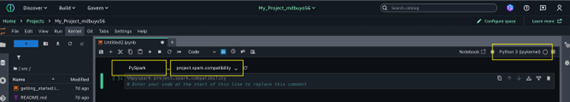
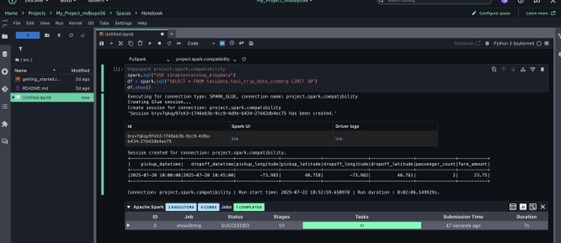
  4. Select Python3 Kernel.
  5. Choose PySpark as the connection type.
  6. Select your table bucket and namespace as the data source for your queries:
    1. For Spark engine, execute query USE s3tablescatalog_blogdata

Querying data using Redshift:

In this section, we walk through how to query the data using Redshift within SageMaker Unified Studio.

  1. From the SageMaker Studio home page, choose your project name in the top center navigation bar.
  2. In the navigation panel, expand the Redshift project folder.
  3. Open the blogdata@s3tablescatalog database.
  4. Expand the taxidata schema.
  5. Under the Tables section, locate and expand taxi_trip_data_iceberg.
  6. Review the table metadata to view all columns and their corresponding data types.
  7. Open the Sample data tab to preview a small, representative subset of records.
  8. Choose Actions.
  9. Select Preview data from the dropdown to open and view the full dataset in the data viewer.

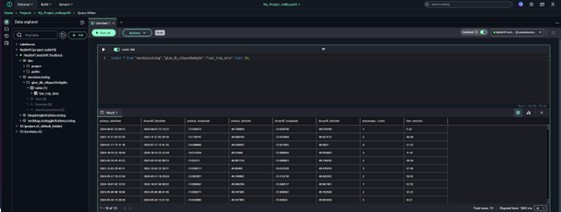
When you select your table, the Query Editor automatically opens with a pre-populated SQL query. This default query retrieves the top 10 records from the table, giving you an instant preview of your data. It uses standard SQL naming conventions, referencing the table by its fully qualified name in the format database_schema.table_name. This approach ensures the query accurately targets the intended table, even in environments with multiple databases or schemas.

Best practices and considerations

The following are some considerations you should take note of.

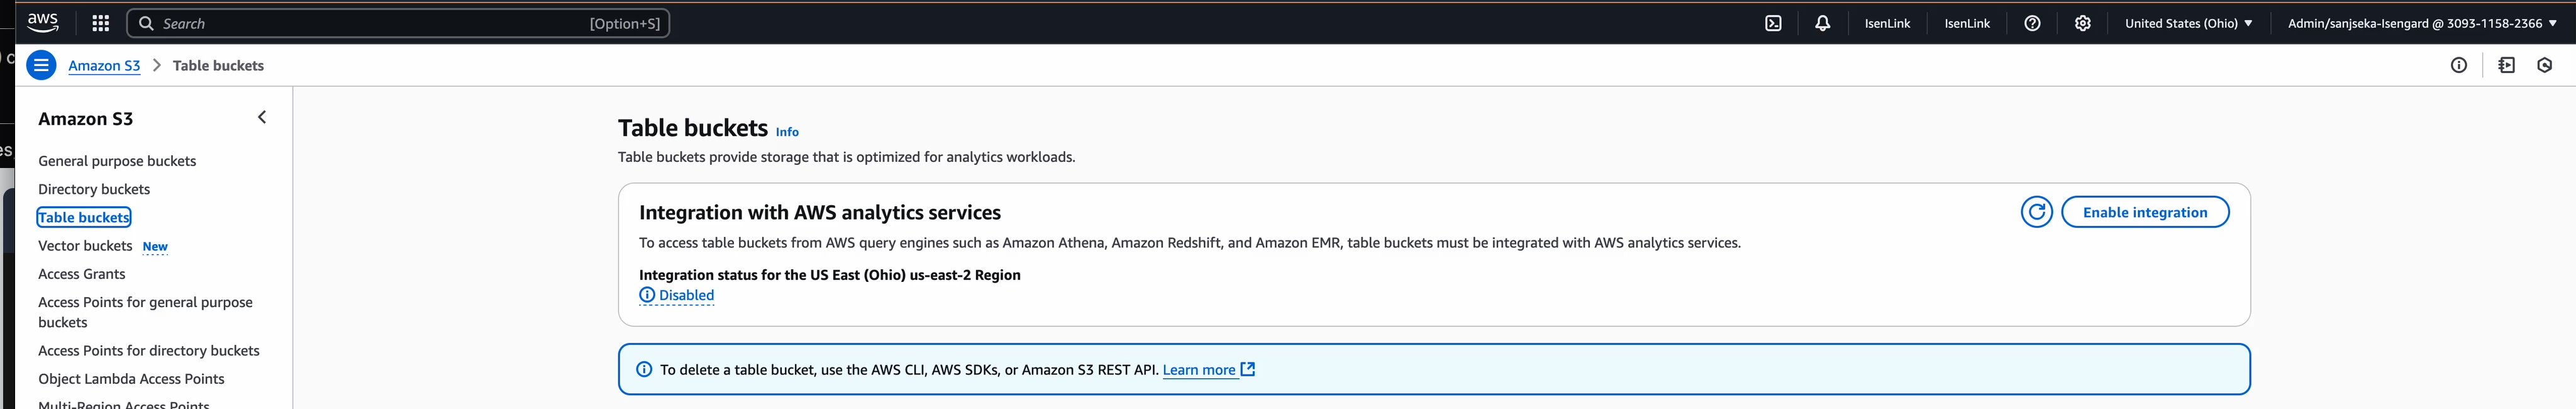
  • When you create an S3 table bucket using the S3 console, integration with AWS analytics services is enabled automatically by default. You can also choose to set up the integration manually through a guided process in the console. Also, when you create S3 Table bucket programmatically using the AWS SDK, or AWS CLI, or REST APIs, the integration with AWS analytics services is not automatically configured. You need to manually perform the steps required to integrate the S3 Table bucket with AWS Glue Data Catalog and Lake Formation, allowing these services to discover and access the table data.
  • When creating an S3 table bucket for use with AWS analytics services like Athena, we recommend using all lowercase letters for the table bucket name. This requirement ensures proper integration and visibility within the AWS analytics ecosystem. Learn more about it from getting started with S3 tables.
  • S3 Tables offer automatic table maintenance features like compaction, snapshot management, and unreferenced file removal to optimize data for analytics workloads. However, there are some limitations to consider. Please read more on it from considerations and limitations for maintenance jobs.

Conclusion

In this post, we discussed how to use SageMaker Unified Studio’s integration with S3 Tables to enhance your data analytics workflows. The post explained the setup process, including creating a Lakehouse catalog with S3 table bucket source, configuring necessary IAM roles, and establishing integration with AWS Glue Data Catalog and Lake Formation. We walked you through practical implementation steps, from creating and managing Apache Iceberg based S3 tables to executing queries through both the Query Editor and JupyterLab with PySpark, as well as accessing and analyzing data using Redshift.

To get started with SageMaker Unified Studio and S3 Tables integration, visit Access Amazon SageMaker Unified Studio documentation.


About authors

Sakti Mishra

Sakti Mishra

Sakti is a Principal Data and AI Solutions Architect at AWS, where he helps customers modernize their data architecture and define end-to end-data strategies, including data security, accessibility, governance, and more. He is also the author of Simplify Big Data Analytics with Amazon EMR and AWS Certified Data Engineer Study Guide. Outside of work, Sakti enjoys learning new technologies, watching movies, and visiting places with family.

Vivek Shrivastava

Vivek Shrivastava

Vivek is a Principal Data Architect, Data Lake in AWS Professional Services. He is a big data enthusiast and holds 14 AWS Certifications. He is passionate about helping customers build scalable and high-performance data analytics solutions in the cloud. In his spare time, he loves reading and finds areas for home automation.

David Pasha

David Pasha

David is a Senior Healthcare and Life Sciences (HCLS) Technical Account Manager with 16 years of expertise in analytics. As an active member of the Analytics Technical Field Community (TFC), he specializes in designing and implementing scalable data warehouse solutions for customers in the cloud.

Debu Panda

Debu Panda

Debu is a Senior Manager, Product Management at AWS. He is an industry leader in analytics, application platform, and database technologies, and has more than 25 years of experience in the IT world.

Building responsive APIs with Amazon API Gateway response streaming

Post Syndicated from Anton Aleksandrov original https://aws.amazon.com/blogs/compute/building-responsive-apis-with-amazon-api-gateway-response-streaming/

Today, AWS announced support for response streaming in Amazon API Gateway to significantly improve the responsiveness of your REST APIs by progressively streaming response payloads back to the client. With this new capability, you can use streamed responses to enhance user experience when building LLM-driven applications (such as AI agents and chatbots), improve time-to-first-byte (TTFB) performance for web and mobile applications, stream large files, and perform long-running operations while reporting incremental progress using protocols such as server-sent events (SSE).

In this post you will learn about this new capability, the challenges it addresses, and how to use response streaming to improve the responsiveness of your applications.

Overview

Consider this scenario – you’re running an AI-powered agentic application that uses an Amazon Bedrock foundation model. Your users interact with the application through an API, asking complex questions that require detailed responses. Before response streaming, users would send their prompts and wait to eventually receive the application response, sometimes for tens of seconds. This awkward pause between questions and responses created a disconnected, unnatural experience.

With the new API Gateway response streaming capability, the interaction through the API becomes much more fluid and natural. As soon as your application starts processing the model response, you can stream it back to your users using the API Gateway.

The following animation illustrates this significant user experience improvement. The prompt on the left is processed using a non-streaming response with user having to wait for several seconds to receive the result. The prompt on the right is using the new API Gateway response streaming, significantly reducing TTFB and improving user experience.

Figure 1. Comparing user experience before (left) and after (right) enabling API Gateway response streaming when returning a response from a Bedrock foundational model.

Your users can now see AI responses appear in real-time, word by word, just like watching someone type. This immediate feedback makes your applications feel more responsive and engaging, keeping users connected throughout the interaction. In addition, you don’t have to worry about response size limits or implement complex workarounds – the streaming happens automatically and efficiently, letting you focus on building great user experiences rather than managing infrastructure constraints.

Understanding response steaming

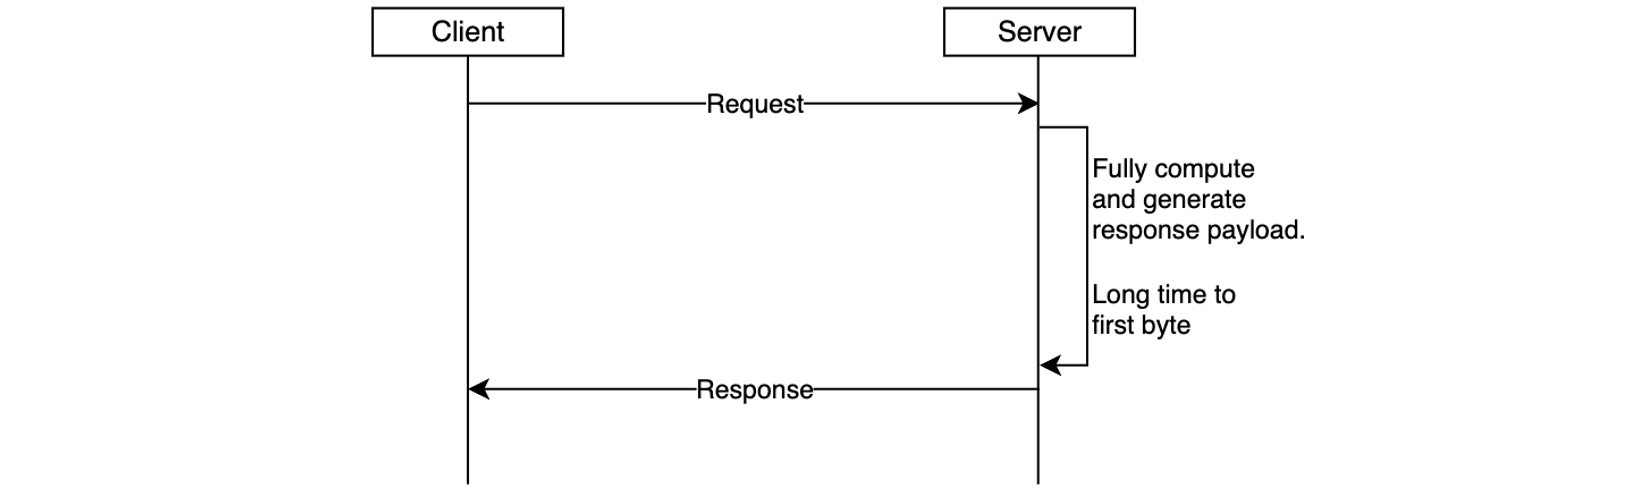
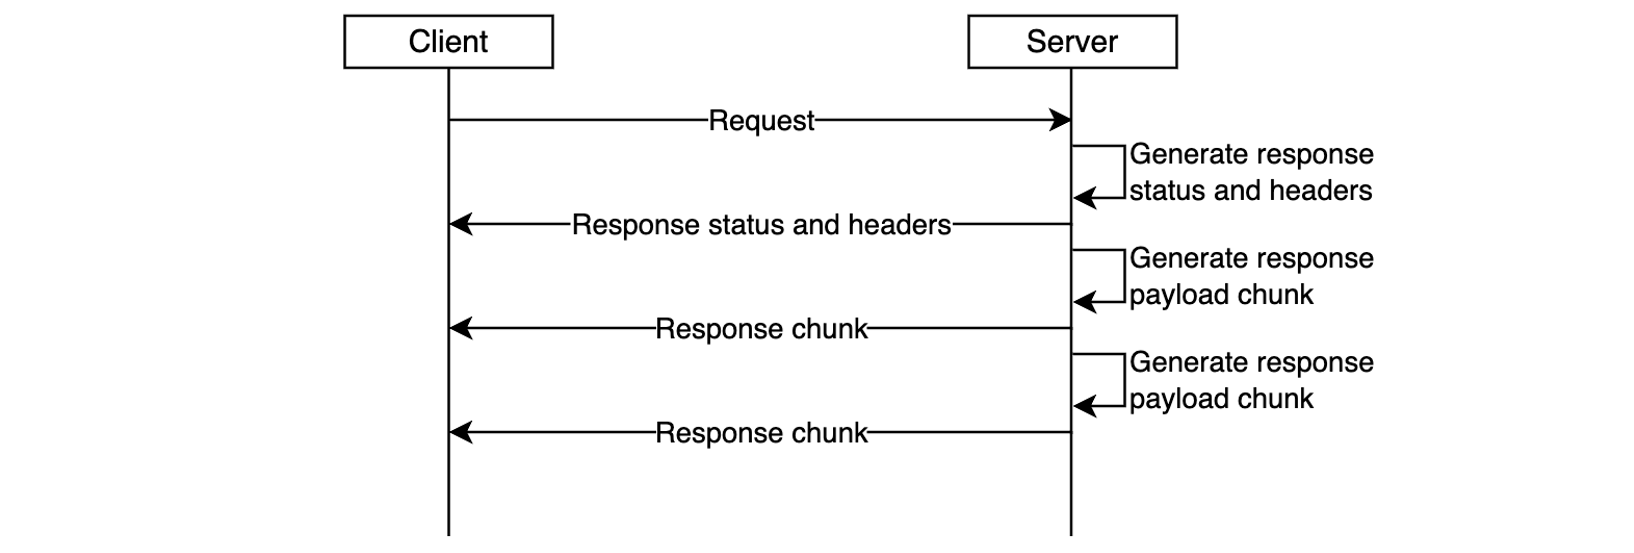
In the traditional request-response model, responses must be fully computed before being sent to the client. This can negatively impact user experience – the client must wait for the complete response to be generated on the server-side and transmitted over-the-wire. This is especially pronounced in interactive, latency-sensitive cloud applications such as AI agents, chatbots, virtual assistants, or music generators.

Figure 2. Response is returned to the client only after it’s been fully generated, increasing time-to-first-byte latency.

Another important scenario is returning larger response payloads, such as images, large documents, or datasets. In some cases, these payloads may exceed the 10 MB response size limit or default integration timeout limit of 29 seconds of API Gateway. Before the launch of response streaming, developers worked around these limitations by using pre-signed Amazon S3 URLs to download large responses or accepting lower RPS for an increase in timeout. While functional, these workarounds introduced additional latency and architectural complexity.

With response streaming support you can address these challenges. You can now update your REST APIs to return streamed responses, significantly enhancing user experience, improving TTFB performance, supporting response payload sizes to exceed 10 MB, and serving requests that can take up to 15 minutes.

Figure 3. Response streaming reduces time-to-first-byte and improves user experience.

The response streaming capability is already delivering significant performance for organizations:

“Working closely with the AWS teams to enable response streaming was instrumental in advancing our roadmap to deliver the most performant storefront experiences for our largest customers at Salesforce Commerce Cloud. Our collaboration exceeded our Core Web Vital goals; we saw our Total Blocking Time metrics drop by over 98%, which will enable our customers to drive higher revenue and conversion rates.”, says Drew Lau, Senior Director of Product Management at Salesforce.

Response streaming is supported for any HTTP-proxy integration, AWS Lambda functions (using proxy integration mode), and private integrations. To get started, configure your API integration to stream the response from your backend, as described in the following sections, and redeploy your API for changes to take effect.

Getting started with response streaming

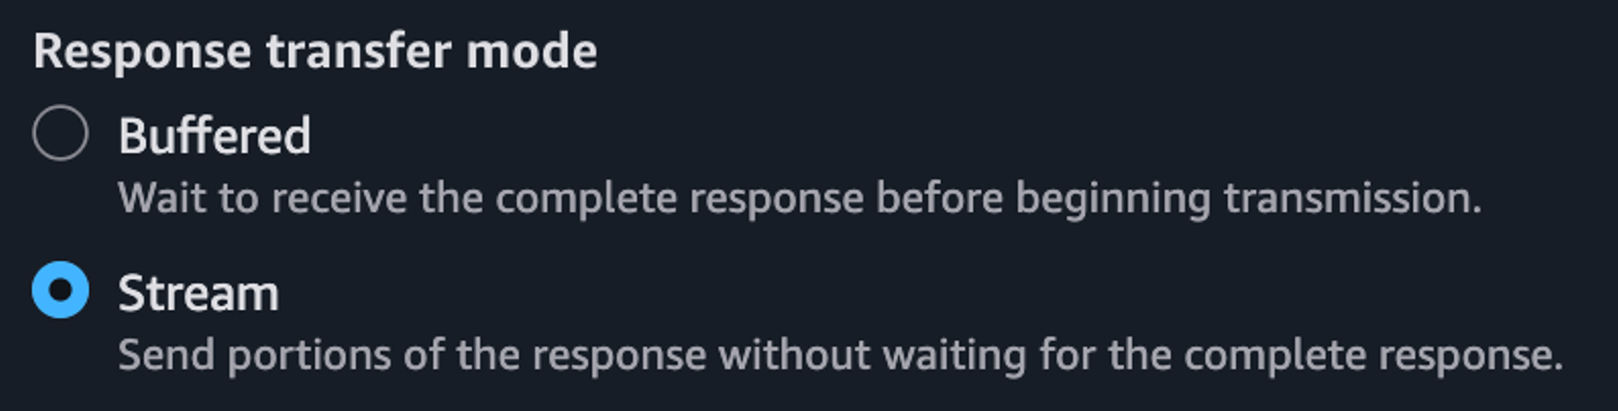
To enable response streaming for your REST APIs, update your integration configuration to set the response transfer mode to STREAM. This enables API Gateway to start streaming the response to the client as soon as response bytes become available. When using response streaming, you can configure request timeout up to 15 minutes. For best time to first byte user experience, AWS strongly recommends your backend integration also implements response streaming.

You can enable response streaming in several different ways, as illustrated in the following snippets:

Using the API Gateway console, when creating method integrations, select Stream for the Response transfer mode.

Figure 4. Enabling response streaming in API Gateway Console.

Setting response transfer mode using the Open API spec:

paths:
  /products:
    get:
      x-amazon-apigateway-integration:
        httpMethod: "GET"
        uri: "https://example.com"
        type: "http_proxy"
        timeoutInMillis: 300000
        responseTransferMode: "STREAM"

Setting response transfer mode using infrastructure-as-code (IaC) frameworks, such as AWS CloudFormation. Note the /response-streaming-invocations Uri fragment, it tells API Gateway to use the Lambda InvokeWithResponseStreaming endpoint:

MyProxyResourceMethod:
  Type: 'AWS::ApiGateway::Method'
  Properties:
    RestApiId: !Ref LambdaSimpleProxy
    ResourceId: !Ref ProxyResource
    HttpMethod: ANY
    Integration:
      Type: AWS_PROXY
      IntegrationHttpMethod: POST
      ResponseTransferMode: STREAM
      Uri: !Sub arn:aws:apigateway:${APIGW_REGION}:lambda:path/2021-11-
           15/functions/${FN_ARN}/response-streaming-invocations

Updating response transfer mode using the AWS CLI:

aws apigw update-integration \
   --rest-api-id a1b2c2 \
   --resource-id aaa111 \
   --http-method GET \
   --patch-operations "op='replace',path='/responseTransferMode',value=STREAM" \
   --region us-west-2

Using response streaming with Lambda functions

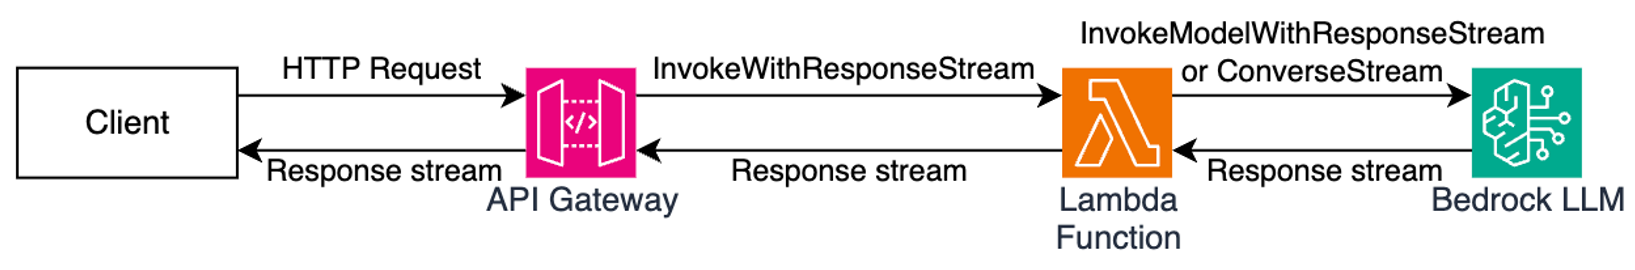
When using Lambda functions as a downstream integration endpoint, your Lambda functions must be streaming-enabled. The API Gateway uses the InvokeWithResponseStreaming API to invoke functions, as illustrated in the following diagram, and requires Lambda proxy integration. See the API Gateway documentation for additional guidance.

Figure 5. Using API Gateway response streaming with Lambda functions for interactive AI applications.

When you use response streaming with Lambda functions, API Gateway expects the handler response stream to contain the following components (in order):

  • JSON response metadata – Must be a valid JSON object and can only contain statusCode, headers, multiValueHeaders, and cookies fields (all optional). Metadata cannot be an empty string; at a minimum it must be an empty JSON object.
  • The 8-null-byte delimiter – Lambda adds this delimiter automatically when you use the built-in awslambda.HttpResponseStream.from() method, as illustrated below. When not using this method, you’re responsible for adding the delimiter yourself.
  • Response payload – Can be empty.

The following code snippet illustrates how you can return a streamed response from your Lambda functions so it will be compatible with API Gateway response streaming:

export const handler = awslambda.streamifyResponse(
   async (event, responseStream, context) => {

      const httpResponseMetadata = {
         statusCode: 200,
         headers: {
            'Content-Type': 'text/plain',
            'X-Custom-Header': 'some-value'
         }
      };

      responseStream = awslambda.HttpResponseStream.from(
         responseStream,
         httpResponseMetadata
      );

      responseStream.write('hello');
      await new Promise(r => setTimeout(r, 1000));
      responseStream.write(' world');
      await new Promise(r => setTimeout(r, 1000));
      responseStream.write('!!!');
      responseStream.end();
   }
);

Refer to the API Gateway documentation for further implementation guidelines.

Using response streaming with HTTP Proxy integrations

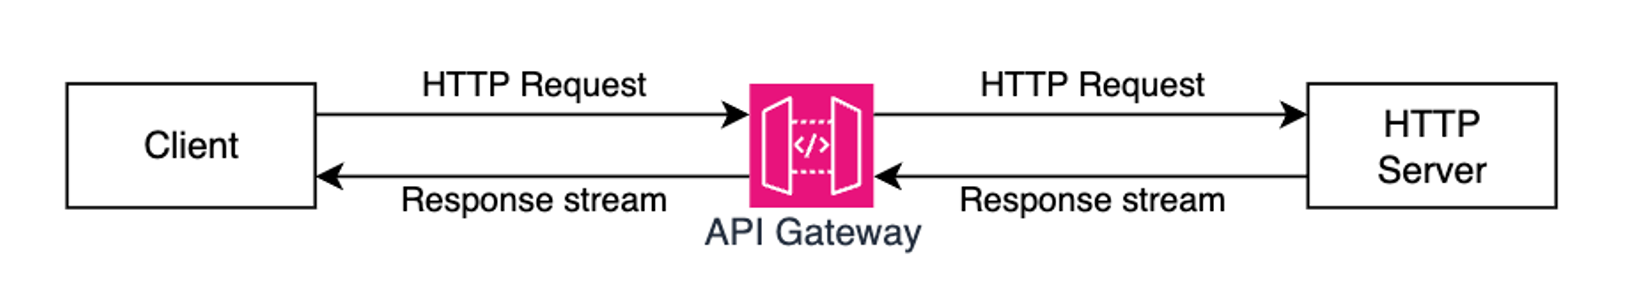
You can stream HTTP responses from your applications used as downstream integration endpoints, for example web servers running on Amazon Elastic Container Service (Amazon ECS) or Amazon Elastic Kubernetes Service (Amazon EKS). In this case, you must use HTTP_PROXY integration and specify the response transfer mode as STREAM (using the console, AWS CLI, or IaC). Redeploy your API after modifying it.

Figure 6. Using API Gateway response streaming with HTTP server applications.

Once API Gateway receives a streaming response from your application, it will wait until the HTTP headers block transfer is complete. Then, it will send to the client an HTTP response status code and headers, followed by the content from your application as it gets received by the API Gateway service. It will continue streaming response from your application to the client until the stream ends (up to 15 minutes).

Many popular API and web application development frameworks provide response streaming abstractions. The following code snippet illustrates how you can implement HTTP response streaming using FastAPI:

app = FastAPI()

async def stream_response():
   yield b"Hello "
   await asyncio.sleep(1)
   yield b"World "
   await asyncio.sleep(1)
   yield b"!"

@app.get("/")
async def main():
   return StreamingResponse(stream_response(), media_type="text/plain")

Adding real-time response streaming to your HTTP clients

Different HTTP clients have different ways to process streamed response fragments as they arrive. The following code snippet illustrates how to process a streamed response with a Node.js application:

const request = http.request(options, (response)=>{
   response.on('data', (chunk) => {
      console.log(chunk);
   });

   response.on('end', () => {
      console.log('Response complete’);
   });
});

request.end();

When using CURL, you can use the –no-buffer argument to print response fragments as they arrive.

curl --no-buffer {URL}

Sample code

Clone this sample project from GitHub to see API Gateway response streaming in action. Follow instructions in the README.md to provision the sample project in your AWS account.

Considerations

Before you enable response streaming, consider:

  • Response streaming is available for REST APIs and can be used with HTTP_PROXY integrations, Lambda integrations (in proxy mode), and private integrations.
  • You can use API Gateway response streaming with any endpoint type, such as Regional, Private, and Edge-optimized, with or without custom domain names.
  • When using response streaming, you can configure response timeouts up to 15 minutes, according to your scenario requirements.
  • All streaming responses from Regional or Private endpoints are subject to a 5-minute idle timeout. All streaming responses from edge-optimized endpoints are subject to a 30-second idle timeout.
  • Within each streaming response, the first 10MB of response payload is not subject to any bandwidth restrictions. Response payload data exceeding 10MB is restricted to 2MB/s.
  • Response streaming is compatible with API Gateway security capabilities such as authorizers, WAF, access controls, TLS/mTLS, request throttling, and access logging.
  • When processing streamed responses, the following features are not supported: response transformation with VTL, integration response caching, and content encoding.
  • Always protect your APIs against unauthorized access and other potential security threats by implementing proper authorization with Lambda Authorizers or Amazon Cognito User Pools. Read REST API protection documentation and API Gateway security documentation for additional details.

Observability

You can continue using existing observability capabilities, such as execution logs, access logs, AWS X-Ray integration, and Amazon CloudWatch metrics with API Gateway response streaming.

In addition to the existing access logs variables, the following new variables are available:

  • $content.integration.responseTransferMode – the response transfer mode of your integration. This can be either BUFFERED or STREAMED.
  • $context.integration.timeToAllHeaders – the time between when API Gateway establishes the integration connection to when it receives all integration response headers from the client.
  • $context.integration.timeToFirstContent – the time between when API Gateway establishes the integration connection to when it receives the first content bytes.

See API Gateway documentation for more information.

Pricing

With this new capability, you continue to pay the same API Invoke rates for streamed responses. Each 10MB of response data, rounded up to the nearest 10MB, is billed as a single request. See API Gateway pricing page for additional details.

Conclusion

The new response streaming capability for Amazon API Gateway enhances how you can build and deliver responsive APIs in the cloud. With immediate streaming of response data as it becomes available, you can significantly improve time-to-first-byte performance and overcome traditional payload size and timeout limitations. This is particularly valuable for AI-powered applications, file transfers, and interactive web experiences that demand real-time responsiveness.

To learn more about API Gateway response streaming see the service documentation.

To learn more about building Serverless architectures see Serverless Land.

Analyze AWS Network Firewall logs using Amazon OpenSearch dashboard

Post Syndicated from Hoorang Broujerdi original https://aws.amazon.com/blogs/security/analyze-aws-network-firewall-logs-using-amazon-opensearch-dashboard/

Amazon CloudWatch and Amazon OpenSearch Service have launched a new dashboard that simplifies the analysis of AWS Network Firewall logs. Previously, in our blog post How to analyze AWS Network Firewall logs using Amazon OpenSearch Service we demonstrated the required services and steps to create an OpenSearch dashboard. The new dashboard removes these extra steps and streamlines the entire process. In this post, I show you how to build and use the new OpenSearch Service dashboards to analyze Network Firewall logs more efficiently.

Network Firewall is a managed security service that protects Amazon Virtual Private Cloud (Amazon VPC) VPCs by monitoring and filtering network traffic. Network Firewall provides stateful inspection, which gives you information that you can use to create custom rules to control incoming and outgoing traffic. It automatically scales, offers high availability, and integrates with other AWS security services, in addition to helping to block unexpected traffic, prevent unauthorized access, and filter traffic based on domains and IP addresses.

Analyzing Network Firewall logs provides you with insight into the traffic entering or leaving your VPC and helps you troubleshoot issues and understand your security posture over time. This analysis is crucial for maintaining effective security controls.

Network Firewall generates three types of logs from its stateful engine:

  • Flow logs: These capture standard network traffic flow information based on your stateless rules
  • Alert logs: These show traffic that matches stateful rules configured with DROP, ALERT, or REJECT actions
  • TLS logs: These provide details about TLS inspection events (requires TLS inspection configuration)

Prerequisites

This post assumes that you’re familiar with the fundamentals of AWS networking concepts and services such as Amazon VPC, subnets, routing tables, and other services such as Network Firewall, Amazon CloudWatch, and OpenSearch Service.

To analyze Network Firewall logs using OpenSearch Service, you must have:

  1. An active Network Firewall in your VPC
  2. CloudWatch log groups configured for:
    1. Flow logs, for example /inspection-nwfw-flow-logs
    2. Alert logs, for example /inspection-nwfw-alert-logs

If you haven’t deployed Network Firewall in your VPC, you can use one of the available Network Firewall deployment architecture templates to create a firewall. After creating a firewall, configure CloudWatch log groups for the firewall flow and alert logs and configure stateful logging. Fine-tune your firewall policy and rule configuration and make sure that you’re routing traffic symmetrically through the firewall. Verify that your CloudWatch log groups are receiving firewall logs. You can do this by navigating to the AWS Management Console for CloudWatch, selecting your log group, and viewing the log streams under the Log streams tab.

With the firewall in the routed path and publishing metrics and log events, you can proceed with creating a Network Firewall OpenSearch dashboard.

Scenario

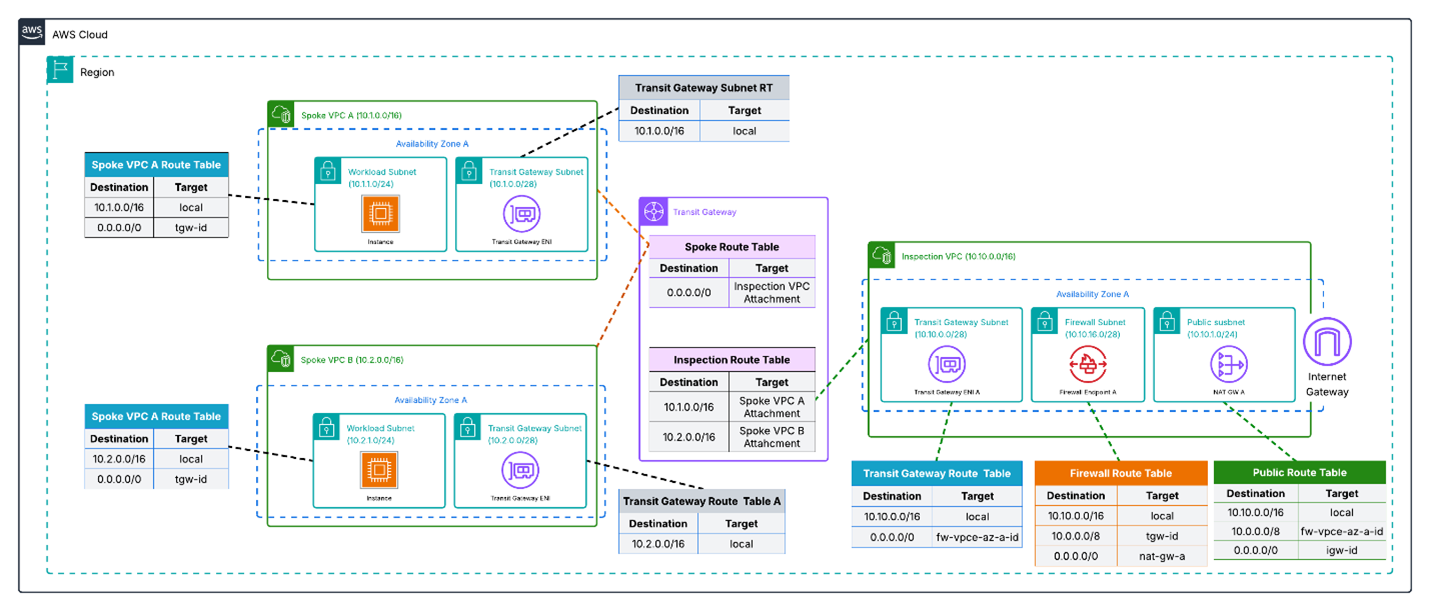
In this post, I show you how to set up a centralized architecture, single Availability Zone deployment as shown in Figure 1. Then, you will create an OpenSearch dashboard for your firewall to monitor and analyze traffic.

Figure 1: Network Firewall centralized architecture, single Availability Zone deployment

Solution deployment

To analyze Network Firewall logs in OpenSearch Service, you first need to create an OpenSearch integration.

To create an OpenSearch Service integration:

  1. Open the Amazon CloudWatch console.
  2. Choose Settings in the navigation pane.
  3. Choose the Logs tab.
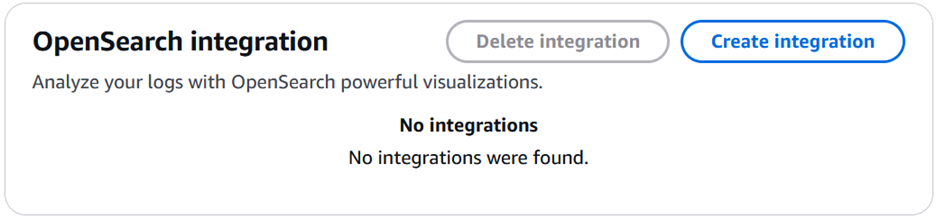
  4. Scroll down to find OpenSearch integration and choose Create integration.

Figure 2: Create an OpenSearch integration

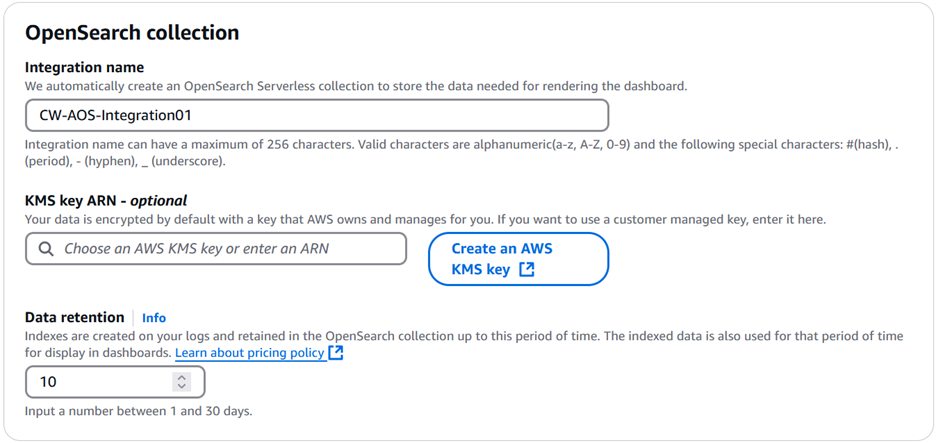
  1. There are three items to be configured under OpenSearch collection:
    1. Enter a name for Integration name. For example, CW-AOS-Integration01.
    2. KMS key ARN – optional is optional. If you leave that empty, your data will be encrypted by default with a key that AWS owns and manages. You also have an option to create and use an AWS Key Management Service (AWS KMS) key.
    3. For Data retention, select a number between 1 and 30 depending on your retention policy. For example, select 10 to retain logs for 10 days.

Figure 3: Configure an OpenSearch collection

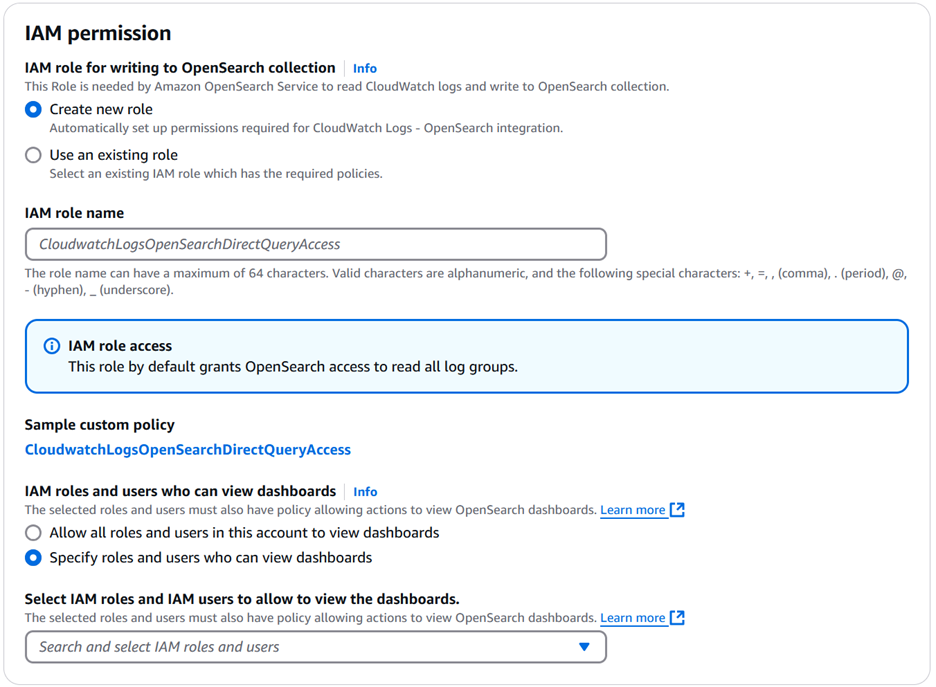
  1. Next, you need to configure AWS Identity and Access Management (IAM) permissions.
    1. For the IAM role for writing to OpenSearch collection, you can either create a new role or use an existing role. If you choose Create new role, then you need to provide an IAM role name. For example, CWLogQueryOS. This role must have permissions to read from all log groups in the account. See Permissions that the integration needs for an example of the permission that the integration needs.
    2. IAM roles and users who can view dashboards defines who can view the dashboards. Select either:
      • Allow all roles and users in this account to view dashboards.
      • Specify roles and users who can view dashboards. By choosing Specify roles…, you can select the IAM roles and users who can view the dashboard.
    3. Choose Confirm integration setup to create the integration. It might take 1–5 minutes for the integration to be created.

Figure 4: Configure IAM permissions

After you receive notification of successful creation of the OpenSearch integration, you can create an OpenSearch dashboard.

To create an OpenSearch dashboard:

  1. Navigate to Amazon CloudWatch console and choose Logs insights in the navigation pane.
  2. In Logs Insights, choose the Analyze with OpenSearch tab.
  3. Choose Create dashboard.
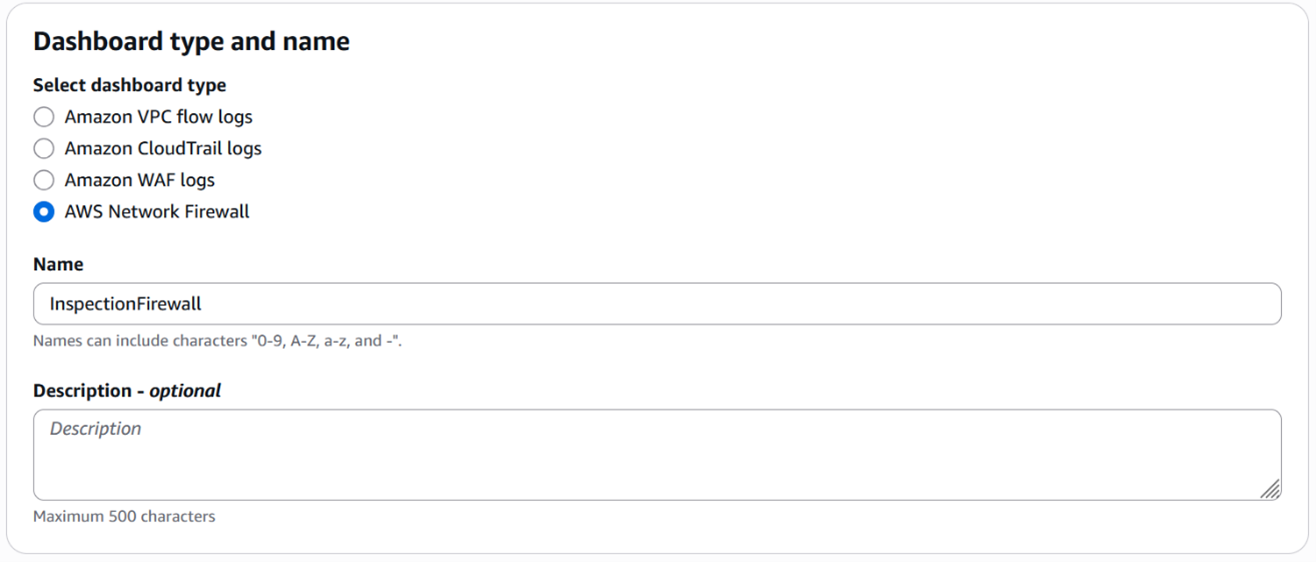
  4. Under Select dashboard type, select AWS Network Firewall.
  5. Enter a name for the dashboard, such as InspectionFirewall.

Figure 5: Select the dashboard type and enter a name

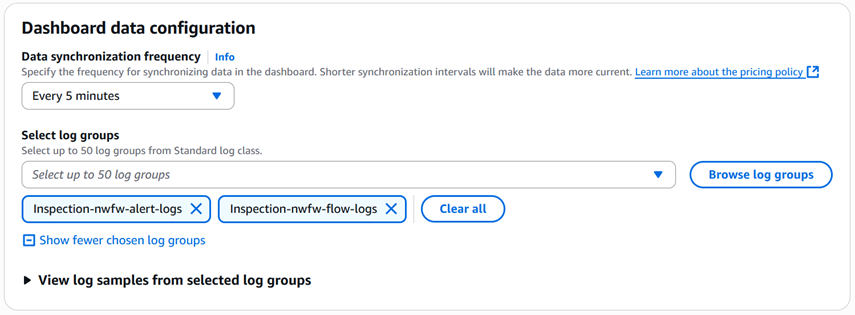
  1. Under Dashboard data configuration, select Every 5 minutes.
  2. Under Select log groups, select Inspection-nwfw-alert-logs and Inspection-nwfw-flow-logs.

Figure 6: Select data synchronization frequency and log groups

  1. Choose Create dashboard. If you have multiple firewalls in your environment, repeat steps 1–8 to create a dashboard for each Firewall.
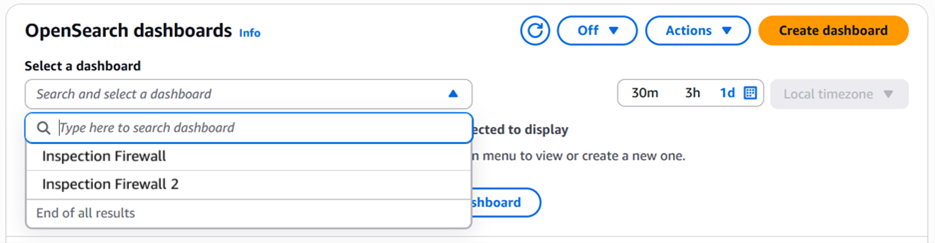
  2. Choose Select a dashboard and select and select a dashboard to view.

Figure 7: View a list of existing firewalls in OpenSearch dashboards

Dashboard overview

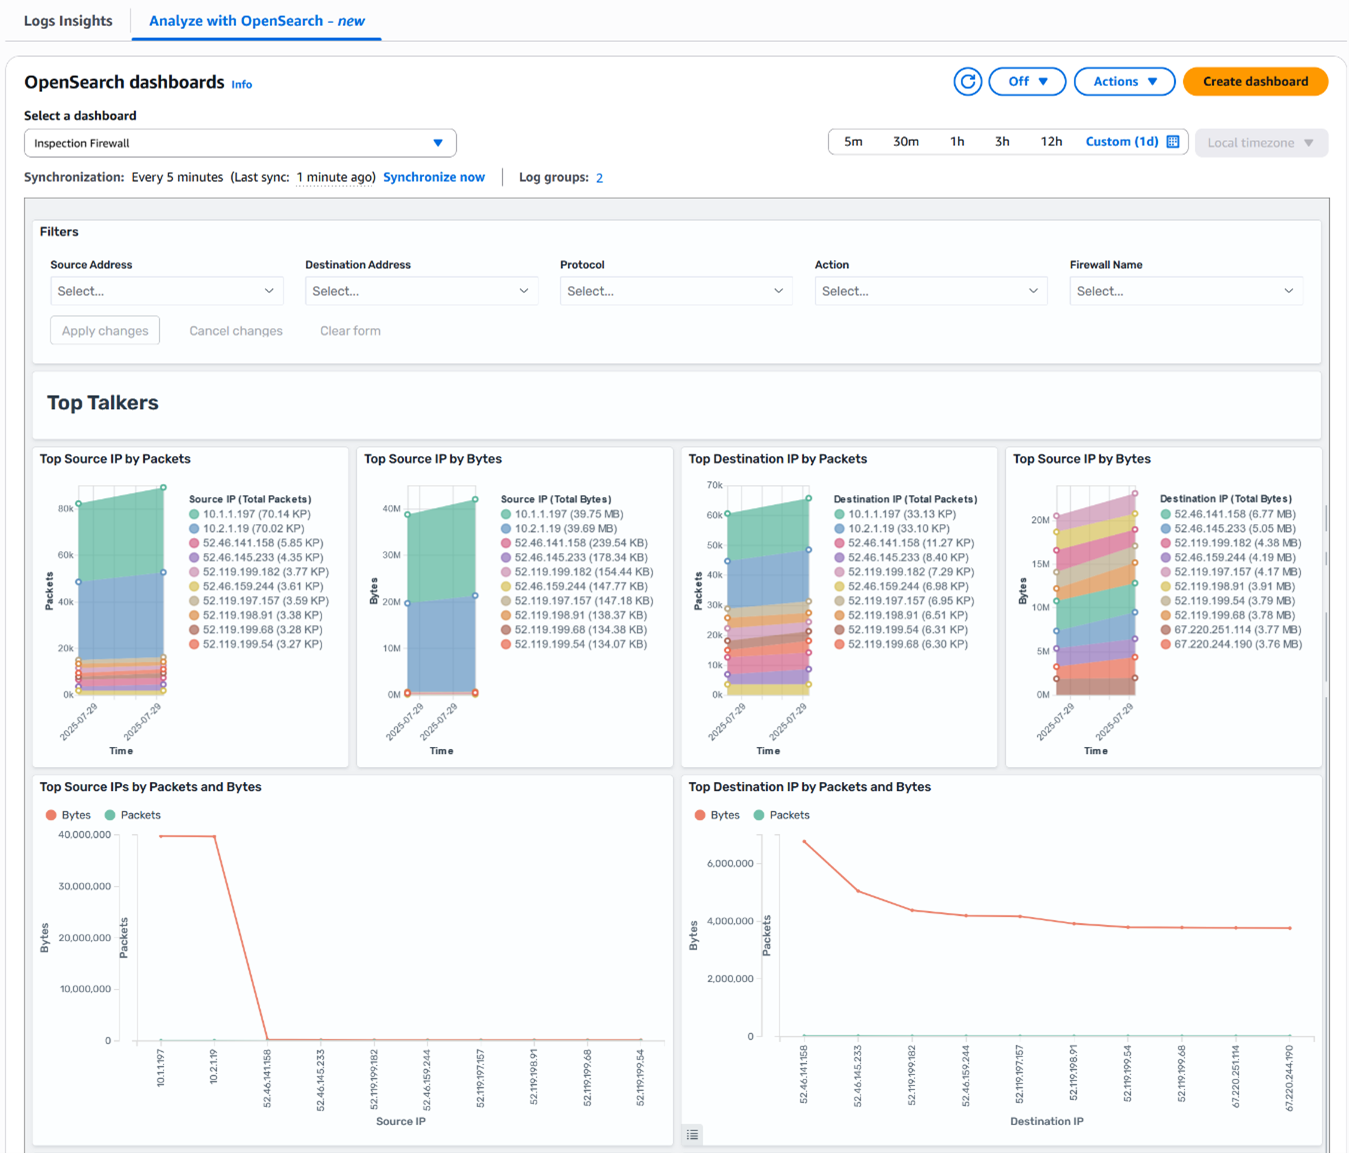
Your new OpenSearch dashboard, similar to Figure 8, provides you with visual insight into some of your firewall events such as:

  • Top talkers
  • Top protocols
  • Alert log analysis
  • Firewall engines

Figure 8: Network Firewall OpenSearch dashboard

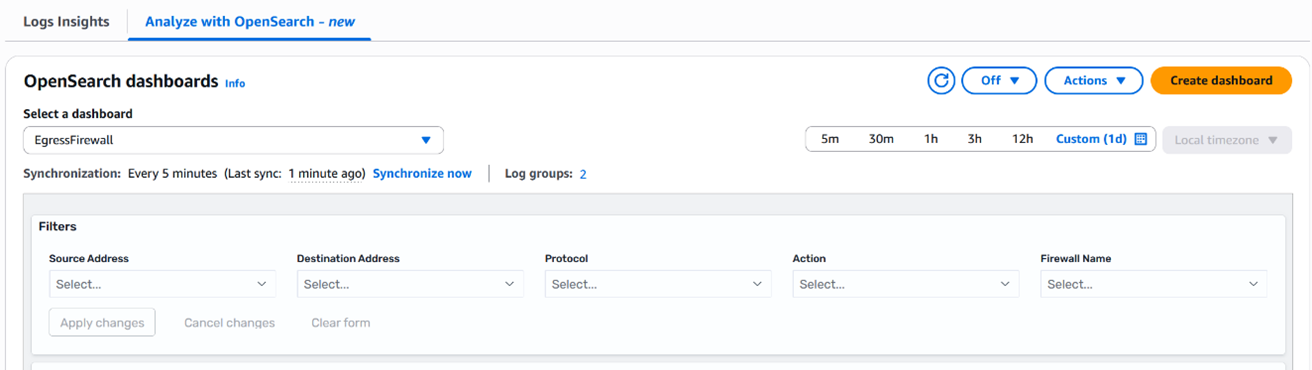
As shown in Figure 9, you can refine your analysis to focus on a specific traffic pattern or security event by using the filters at the top of the dashboard to focus on traffic based on:

  • Source or destination addresses
  • Protocols
  • Actions
  • Firewall names

Figure 9: Network Firewall OpenSearch dashboard filters

To dive deep into a widget:

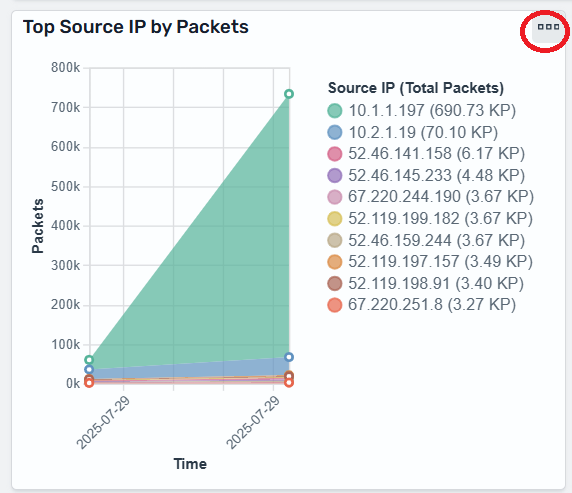
  • Hover your cursor over a widget in the dashboard to reveal the options menu icon (…) in the top right corner of the widget.
  • Choose the options menu icon (…) to maximize the widget or open the Inspect view, as shown in Figure 10.

Figure 10: Top Source IP by Packets widget showing the options menu icon (…)

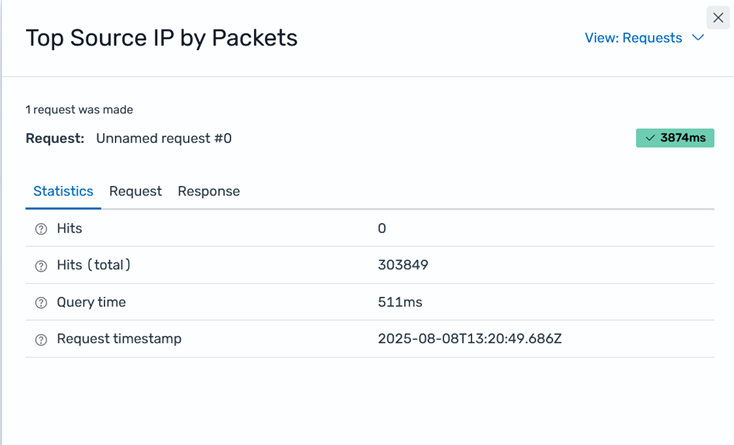
Figure 11 shows the Inspect window for the Top Source IP by Packets widget. In this window, you can get information by selecting Statistics, Request, or Response.

Figure 11: Inspect window for Top Source IP by Packets widget

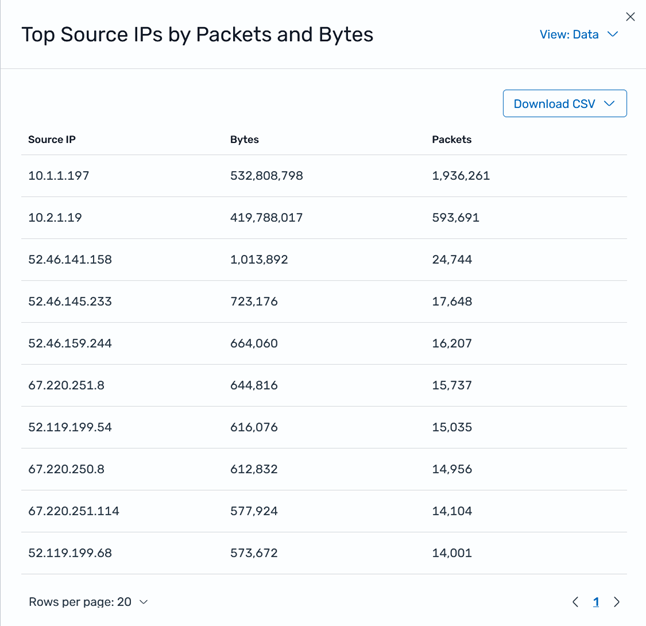
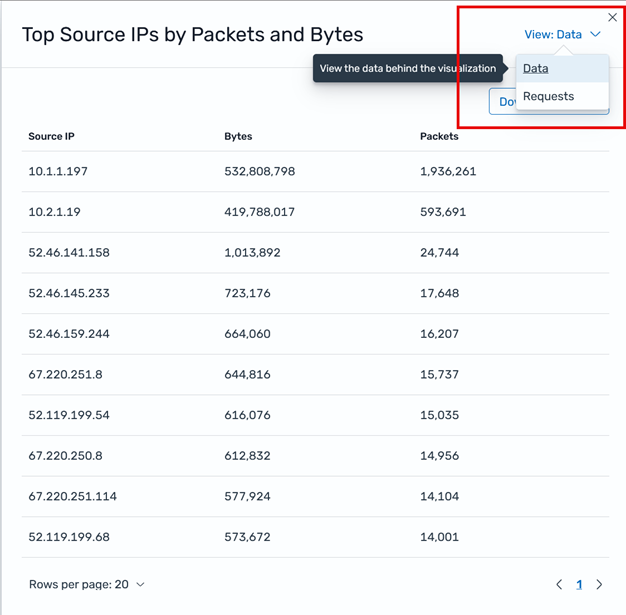
This window might look different depending on the widget you choose. Some widget options menus provide more information than others and include an option to download the information in CSV format. For example, you can use the Top Source IPs by Packets and Bytes widget to view data and download it in CSV format, as shown in Figure 12.

Figure 12: Inspect window for Top Source IPs by Packets and Bytes widget

When using the Top Source IPs by Packets and Bytes, you can use the View menu to switch the view from Data to Requests to access more information, as shown in Figure 13.

Figure 13: Switch the Inspect window view for Top Source IPs by Packets and Bytes widgets between Data and Requests

Example use cases

The following are some examples of how you can use the Network Firewall OpenSearch dashboard to facilitate monitoring and troubleshooting:

  • Identify unusual traffic patterns:
    • Use the Top Source IPs by Packets and Bytes widget
    • Look for unexpected spikes or outliers
  • Monitor security rule effectiveness:
    • Analyze the Alert Log Analysis section
    • Track which rules are triggering most frequently
  • Troubleshoot connectivity issues:
    • Use filters to isolate traffic for specific IP ranges
    • Examine flow logs for blocked connections
  • Verify compliance:
    • Review TLS logs to verify encryption standards
    • Use filters to focus on traffic to and from sensitive resources

Cost considerations

You will incur charges for AWS Network Firewall and the OpenSearch services used. For more information, see AWS Network Firewall Pricing and Amazon CloudWatch Pricing.

Conclusion

By building Amazon OpenSearch Service dashboards for AWS Network Firewall logs to transform complex security data into actionable insights, you can monitor and analyze your network security posture more effectively. By combining the robust security features of Network Firewall with the powerful visualization capabilities offered by OpenSearch Service, you gain real-time visibility into network traffic patterns, can quickly identify potential security threats, and streamline your troubleshooting workflows. This solution reduces the mean time to detect security incidents and improves operational efficiency through visual analytics to support data-driven decision making. Whether you’re focusing on threat detection, compliance monitoring, or security optimization, these dashboards can provide the visibility and insights needed to strengthen your overall security posture.


If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Hoorang Broujerdi

Hoorang Broujerdi

Hoorang is a Senior Technical Account Manager at AWS Enterprise Support with more than two decades of experience. He helps organizations architect resilient, secure, and efficient cloud environments, guiding them through complex networking challenges and large-scale infrastructure transformations. He has helped numerous organizations enhance their cloud operations through targeted optimizations, robust architectures, and best-practice implementations.

Post-quantum (ML-DSA) code signing with AWS Private CA and AWS KMS

Post Syndicated from Panos Kampanakis original https://aws.amazon.com/blogs/security/post-quantum-ml-dsa-code-signing-with-aws-private-ca-and-aws-kms/

Following our recent announcement of ML-DSA support in AWS Key Management Service (AWS KMS), we just introduced post-quantum ML-DSA signature support in AWS Private Certificate Authority (AWS Private CA). Customers can use AWS Private CA to create and manage their own private public key infrastructure (PKI) hierarchies. Through this integration, you can establish and use customer-managed quantum-resistant roots of trust for code signing, device authentication, outside (of AWS) workload authentication with AWS IAM Roles Anywhere, or communication tunnels such as IKEv2/IPsec or Mutual TLS (mTLS) using private PKI.

As outlined in the AWS post-quantum cryptography migration plan, establishing quantum-resistant roots of trust is critical for systems that need to maintain security for extended periods of time. ML-DSA, a signature scheme standardized in FIPS 204, provides quantum resistance while maintaining the performance characteristics needed for deployments at scale.

Previously, we shared how to use AWS Private CA and AWS KMS for code signing. In this post, we show you how to combine the post-quantum signing capability provided by AWS KMS with post-quantum code-signing PKI from AWS Private CA. Consumers of signed code that have been pre-provisioned with the post-quantum PKI roots can rest assured that the software could not have been forged by an adversary with a cryptographically relevant quantum computer (CRQC). For demonstration purposes, we use the diy-code-signing-kms-private-ca sample program, which uses the AWS SDK for Java. This code creates a PKI infrastructure, generates a code-signing certificate, signs binary code, and verifies the signature. Although we break down the steps to demonstrate the functionality in this post, you can run the Runner as-is to see it in action with commands found in the README file.

This post uses the Cryptographic Message Syntax (CMS) standard for encapsulating the signatures generated for input binary data. It stores the signature, X.509 certificate, and chain used to establish trust. The signature, known as a detached signature, doesn’t contain the original data. The detached signature can be used together with the original file, which was signed with standard tools such as OpenSSL natively to validate the authenticity of the file.

Create a post-quantum PKI hierarchy

For this post, we will use AWS Private CA to introduce a code-signing PKI. It will consist of a root CA to sign a subordinate CA, and a code-signing certificate signed by the subordinate CA. The whole chain will consist of quantum-resistant ML-DSA certificates.

CA hierarchy creation

First, the post-quantum CA hierarchy must be created with ML-DSA. In this example, we use the ML-DSA-65 variant of the post-quantum signature algorithm. You can do this with the AWS Java SDK as shown in the Runner.java file:

PrivateCA rootPrivateCA = PrivateCA.builder()
	.withCommonName(ROOT_COMMON_NAME)
	.withType(CertificateAuthorityType.ROOT)
	.withAlgorithmFamily(ML_DSA_65_ALGORITHM_FAMILY)
	.getOrCreate();

PrivateCA subordinatePrivateCA = PrivateCA.builder()
    .withIssuer(rootPrivateCA).withCommonName(SUBORDINATE_COMMON_NAME)
    .withType(CertificateAuthorityType.SUBORDINATE)
	.withAlgorithmFamily(ML_DSA_65_ALGORITHM_FAMILY)
    .getOrCreate();

Code-signer creation

For code signing, you need an asymmetric key pair and a code-signing certificate. The asymmetric ML-DSA key pair is generated in AWS KMS and the code-signing certificate is issued by AWS Private CA.

Create an ML-DSA key pair in AWS KMS

First, you must create an asymmetric key pair for code signing operations. Similar to the creation of the hierarchy, the AWS Java SDK can be used to create that AWS KMS key (key pair). Signing will be taking place with the key pair’s private key in AWS KMS. The corresponding public key will be in the code-signing leaf certificate signed by the subordinate CA. These calls are performed as part of the main method within the Runner.java file:

AsymmetricCMK codeSigningCMK = AsymmetricCMK
    .builder().withAlias(CMK_ALIAS)
	.withAlgorithmFamily(ML_DSA_65_ALGORITHM_FAMILY)
    .getOrCreate();

Alternatively, you can generate the key pair in AWS KMS with the AWS Management Console or the AWS Command Line Interface (AWS CLI) as shown in the ML-DSA KMS security blog.

Issue a code-signing certificate

Creating a certificate signing request (CSR) using AWS Private CA is a two-step process. First, you must create a CSR that contains both an identity (Subject) and the previously created AWS KMS public key. The following code snippet in Runner.java accomplishes this:

String codeSigningCSR = codeSigningCMK
	.generateCSR(END_ENTITY_COMMON_NAME);

OpenSSL 3.5 or later can parse this CSR to view its content with the following command if the CSR contents have been written to disk at csr.pem:

openssl req -in csr.pem -inform pem -text -noout
Certificate Request:
	Data:
		Version: 1 (0x0)
		Subject: CN=CodeSigningCertificate
		Subject Public Key Info:
			Public Key Algorithm: ML-DSA-65
				ML-DSA-65 Public-Key:
				pub:
					<Public Key Data>   
		Attributes:
			Requested Extensions:
				X509v3 Basic Constraints:
					CA:FALSE
	Signature Algorithm: ML-DSA-65
	Signature Value:
		<Signature Data>

You can see that the CSR contains an ML-DSA-65 public key. Its corresponding private key will be used to sign code.

The CSR is used by the subordinate CA to issue the code-signing certificate. Note that the code-signing template is used in the templateArn of the IssueCertificate request in the relevant PrivateCA.java file. The inclusion of this template helps ensure that AWS Private CA will issue a certificate with the correct Key Usage (KU) and Extended Key Usage (EKU) extension values, regardless of the values presented in the CSR.

IssueCertificateRequest issueCertificateRequest = IssueCertificateRequest.builder()
	.idempotencyToken(UUID.randomUUID().toString())
	.certificateAuthorityArn(subordinatePrivateCA.arn())
	.csr(SdkBytes.fromUtf8String(csr))
	.signingAlgorithm(algorithmFamily.getPcaSigningAlgorithm())
	.templateArn("arn:aws:acm-pca:::template/CodeSigningCertificate/V1")
	.validity(validity)
	.build();

IssueCertificateResponse issueCertificateResponse = client
	.issueCertificate(issueCertificateRequest);

String certificateArn = issueCertificateResponse.certificateArn();

GetCertificateRequest getCertificateRequest = GetCertificateRequest.builder()
	.certificateAuthorityArn(ca.arn())
	.certificateArn(certificateArn)
	.build();

The response includes the ML-DSA-65 code-signing certificate. You can use OpenSSL 3.5 or later to inspect the contents of the certificate after you save it to a file named code-signing-cert.pem:

openssl x509 -in code-signing-cert.pem -inform pem -text -noout
Certificate:
	Data:
		Version: 3 (0x2)
		Serial Number:
			1a:15:af:1e:64:8d:cd:29:b4:dc:66:2a:8b:1e:ee:b0
		Signature Algorithm: ML-DSA-65
		Issuer: CN=CodeSigningSubordinate-MLDSA65
		Validity
			Not Before: Sep 24 13:10:38 2025 GMT
			Not After : Sep 24 14:10:38 2026 GMT
		Subject: CN=CodeSigningCertificate
		Subject Public Key Info:
			Public Key Algorithm: ML-DSA-65
				ML-DSA-65 Public-Key:
				pub:
					<Public Key Data>
		X509v3 extensions:
			X509v3 Basic Constraints:
				CA:FALSE
			X509v3 Authority Key Identifier:
B7:EF:2E:C9:7A:A8:7E:B5:D6:2D:9A:3F:C7:A7:F8:9D:74:01:6A:EF
			X509v3 Subject Key Identifier:

7F:63:35:0C:56:F8:ED:F1:2A:DF:B5:2E:7C:F1:2C:D9:A0:0E:63:B6
			X509v3 Key Usage: critical
				Digital Signature
			X509v3 Extended Key Usage: critical
				Code Signing
	Signature Algorithm: ML-DSA-65
	Signature Value:
		<Signature Data>

You can see that the certificate includes the ML-DSA-65 public key of the code-signing key pair and the ML-DSA-65 signature from the subordinate CA. You also see the KU and the EKU values, which represent a code-signing certificate from the AWS Private CA template.

Sign code

At this point, you have set up the code-signing PKI, have a code-signing certificate issued by AWS Private CA and a corresponding ML-DSA key pair residing in KMS.

The Java SDK can be used to generate a CMS signature for a code binary file. In the background, this is accomplished by calling the AWS KMS Sign API with the ML-DSA key pair as shown in Runner.java. The following is part of the Java code. This first snippet involves building a certificate chain and then using it along with the code-signing AWS KMS key, the signer’s certificate, and <DATA_TO_SIGN>, the byte array representation of the code file, to generate the detached signature in a CMS structure.

	// Parse code-signing certificate from PEM
	X509CertificateHolder signerCert = CertificateUtils
		.fromPEM(codeSigningCertificate.certificate());

	Collection<X509CertificateHolder> chainCerts = CertificateUtils
		.toCertificateHolders(codeSigningCertificate.certificateChain());

	// Build certificate chain including code-signing cert and intermediate certs
	Collection<X509CertificateHolder> certChain = new ArrayList<> ();
	certChain.add(signerCert);

	// Parse certificate chain
	for (X509CertificateHolder chainCert : chainCerts) {
		if (!chainCert.equals(signerCert)) {
			certChain.add(chainCert);
		}
	}

	// Create detached CMS signature
	CMSCodeSigningObject cmsCodeSigningObject = CMSCodeSigningObject
		.createDetachedSignature(
			codeSigningCMK,
			ML_DSA_65_ALGORITHM_FAMILY,
			<DATA_TO_SIGN>,
			signerCert,
			certChain);

The code-signing object is written to disk in signature-MLDSA65.p7s. You can inspect it with OpenSSL 3.5 or later:

openssl cms -cmsout -in signature-MLDSA65.p7s -inform DER -print
CMS_ContentInfo:
	contentType: pkcs7-signedData (1.2.840.113549.1.7.2)
	d.signedData:
		version: 1
		digestAlgorithms:
			algorithm: shake256 (2.16.840.1.101.3.4.2.12)
			parameter: <ABSENT>
		encapContentInfo:
			eContentType: pkcs7-data (1.2.840.113549.1.7.1)
			eContent: <ABSENT>
		certificates:
			d.certificate:
				cert_info:
					version: 2
					serialNumber: 0xD0B2937F5BABC80AD55C0A90E1DE7057
					signature:
						algorithm: ML-DSA-65 (2.16.840.1.101.3.4.3.18)
						parameter: <ABSENT>
					issuer:			CN=CodeSigningSubordinate-MLDSA65
					validity:
						notBefore: Oct 28 15:05:27 2025 GMT
						notAfter: Oct 28 16:05:26 2026 GMT
					subject:		CN=CodeSigningCertificate
					key:		X509_PUBKEY:
						algor:
							algorithm: ML-DSA-65 (2.16.840.1.101.3.4.3.18)
							parameter: <ABSENT>
						public_key:(0 unused bits)
							...
						issuerUID: <ABSENT>
						subjectUID: <ABSENT>
						extensions:
							object: X509v3 Basic Constraints (2.5.29.19)
							critical: FALSE
							value:
								0000 - 30 00 0.
                                    
							object: X509v3 Authority Key Identifier (2.5.29.35)
							critical: FALSE
							value:
								0000 - 30 16 80 14 b7 ef 2e c9-7a a8 7e b5 d60.......z.~..
								000d - 2d 9a 3f c7 a7 f8 9d 74-01 6a ef-.?....t.j.

                        	object: X509v3 Subject Key Identifier (2.5.29.14)
							critical: FALSE
							value:
								0000 - 04 14 7f 63 35 0c 56 f8-ed f1 2a df b5...c5.V...*..
								000d - 2e 7c f1 2c d9 a0 0e 63-b6.|.,...c.

                         	object: X509v3 Key Usage (2.5.29.15)
							critical: TRUE
							value:
								0000 - 03 02 07 80....
                                    
							object: X509v3 Extended Key Usage (2.5.29.37)
							critical: TRUE
							value:
								0000 - 30 0a 06 08 2b 06 01 05-05 07 03 030...+.......
					sig_alg:
						algorithm: ML-DSA-65 (2.16.840.1.101.3.4.3.18)
						parameter: <ABSENT>
					signature:(0 unused bits)
						...
		d.certificate:
			cert_info:
			version: 2
			serialNumber: 29577999257397559174219641462943780786
			signature:
				algorithm: ML-DSA-65 (2.16.840.1.101.3.4.3.18)
				parameter: <ABSENT>
				issuer:			CN=CodeSigningRoot-MLDSA65
				[...]
                
		d.certificate:
			cert_info:
			version: 2
			serialNumber: 0xB9419A2C5D2422B3A58A5B449546D74B
			signature:
				algorithm: ML-DSA-65 (2.16.840.1.101.3.4.3.18)
				parameter: <ABSENT>
				issuer:			CN=CodeSigningRoot-MLDSA65
				[...]
	crls:
		<ABSENT>
	signerInfos:
		version: 1
		d.issuerAndSerialNumber:
			issuer:				CN=CodeSigningSubordinate-MLDSA65
			serialNumber: 0xD0B2937F5BABC80AD55C0A90E1DE7057
		digestAlgorithm:
			algorithm: shake256 (2.16.840.1.101.3.4.2.12)
			parameter: <ABSENT>
		signedAttrs:
			object: contentType (1.2.840.113549.1.9.3)
			set:
				OBJECT:pkcs7-data (1.2.840.113549.1.7.1)

			object: signingTime (1.2.840.113549.1.9.5)
			set:
				UTCTIME:Oct 28 16:05:27 2025 GMT

			object: id-aa-CMSAlgorithmProtection (1.2.840.113549.1.9.52)
			set:
				SEQUENCE:
	0:d=0hl=2 l=26 cons: SEQUENCE
	2:d=1hl=2 l=11 cons:SEQUENCE
	4:d=2hl=2 l=9 prim:OBJECT:shake256
	15:d=1hl=2 l=11 cons:cont [ 1 ]
	17:d=2hl=2 l=9 prim:OBJECT:ML-DSA-65

        	object: messageDigest (1.2.840.113549.1.9.4)
			set:
				OCTET STRING:
					...
		signatureAlgorithm:
			algorithm: ML-DSA-65 (2.16.840.1.101.3.4.3.18)
			parameter: <ABSENT>
		signature:
			[...]

The CMS signature object directly encapsulates both the code-signing certificate and the subordinate CA certificate. It’s expected that the root certificate will reside in a customer-managed trust store. In addition to these certificates, the CMS object also contains the digest of the input data within the signedAttrs of the signerInfos in the ASN.1 structure. The digest algorithm is SHAKE256 and the OCTET STRING represents the binary digest itself. The use of ML-DSA in CMS is specified in RFC9882.

Note: Although this example uses one ML-DSA signature, some use cases might include dual signatures, a traditional and a quantum-resistant one. Such signed artifacts can be backwards compatible with legacy verifiers that support and can only verify the traditional signature. Upgraded verifiers can verify both signatures.

Verify signed code

Before loading a signed code artifact, its signature needs to be verified. That includes verifying the signature of the code and validating the certificate chain to the trusted root CA. The following code snippet from the main method within the file Runner.java is used for the certificate chain validation and the signature in the code object:

X509CertificateHolder rootCACertificate = CertificateUtils.fromPEM(rootCACertificatePEM); 
cmsCodeSigningObject.verifyDetachedSignature(<DATA_TO_SIGN>, rootCACertificate);

The preceding code retrieves the ML-DSA public key from the code-signing certificate; AWS access or credentials aren’t needed to validate the signature. Entities that have the root CA certificate loaded in their trust store can verify it without needing access to the AWS KMS verify API.

Note: The Runner.java implementation doesn’t use a certificate trust store that’s either part of a browser or part of a file system within the resident operating system of a device or a server. The trust store is placed in an instance of a Java class object for the purpose of this post. If you’re planning to use this code-signing example in a production system, you must change the implementation to use a trust store on the host. To do so, you can build and distribute a secure trust store that includes the root CA certificate.

Alternatively, OpenSSL 3.5 or later can be used to validate the detached signature of the provided input data file with root-ca-MLDSA65.pem, the provided root CA certificate from AWS Private CA.

openssl cms -verify -in signature-MLDSA65.p7s -content <input-data-file> \
            -CAfile root-ca-MLDSA65.pem -inform DER -purpose any \
            -binary -out /dev/null
CMS Verification successful

Note: Although this post focused on code-signing, AWS Private CA can enable post-quantum ML-DSA authentication for other private PKI use cases. In one scenario, applications outside of AWS can access AWS resources by temporarily using certificate-based authentication and swapping it with AWS credentials with AWS IAM Roles Anywhere. AWS IAM Roles Anywhere now supports ML-DSA PKIs like the one created in this post. In another scenario, an mTLS client or IKEv2/IPsec peer could use an ML-DSA certificate issued by AWS Private CA to be authenticated by a server or peer respectively who has been pre-provisioned with the post-quantum PKI root certificate.

Conclusion

This announcement marks an important milestone for post-quantum authentication. With the introduction of ML-DSA X.509 certificates in AWS Private CA, customers can bring quantum resistance to their private PKI use cases. These use cases include client authentication for mTLS or IKEv2/IPsec tunnels, IAM Roles Anywhere, or applications that use private PKI authentication. ML-DSA certificates with AWS Private CA and signing with AWS KMS also enable post-quantum code-singing and establishing post-quantum long-lived roots of trust for devices designed to operate for a long time even after CRQCs became available. Learn more about post-quantum cryptography in general and the overall AWS plan to migrate to post-quantum cryptography.


If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Security, Identity, & Compliance re:Post or contact AWS Support. For more details regarding AWS PQC efforts, refer to our PQC page.
 

Panos Kampanakis

Panos Kampanakis

Panos is a Principal Security Engineer at AWS. He has experience with cybersecurity, applied cryptography, security automation, and vulnerability management. He has coauthored publications on cybersecurity and participated in various security standards bodies to provide common interoperable protocols and languages for security information sharing, cryptography, and public-key infrastructure. Currently, he works with engineers and industry standards partners to provide cryptographically secure tools, protocols, and standards.

Jake Massimo

Jake Massimo

Jake is a Senior Applied Scientist on the AWS Cryptography team. His work interfaces Amazon with the global cryptographic community through international conferences, academic literature, and standards organizations and influences the adoption of post-quantum cloud-scale cryptographic technology. Recently, his focus has been architecting AWS post-quantum cryptographic capabilities, including core libraries and infrastructure so that AWS and customers can seamlessly transition to quantum-safe cryptography.

Author

Kyle Schultheiss

Kyle is a Senior Software Engineer on the AWS Cryptography team. He has been working on the AWS Private Certificate Authority service since its inception in 2018. In prior roles, he contributed to other AWS services such as Amazon Virtual Private Cloud, Amazon EC2, and Amazon Route 53.

Handle unpredictable processing times with operational consistency when integrating asynchronous AWS services with an AWS Step Functions state machine

Post Syndicated from Philip Whiteside original https://aws.amazon.com/blogs/compute/handle-unpredictable-processing-times-with-operational-consistency-when-integrating-asynchronous-aws-services-with-an-aws-step-functions-state-machine/

Integrating asynchronous AWS services with an AWS Step Functions state machine, presents a challenge when building serverless applications on Amazon Web Services (AWS). Services such as Amazon Translate, Amazon Macie, and Amazon Bedrock Data Automation (BDA) excel at handling long-running operations that can take more than 10 minutes to complete because of their asynchronous nature. Asynchronous services return an immediate 200 OK response, indicating that the request has succeeded, upon job submission (see the API response syntax of StartTextTranslationJob in Amazon Translate, CreateClassificationJob in Macie, and InvokeDataAutomationAsync in BDA), rather than waiting for the actual task completion and results.

In this post, we explore using AWS Step Function state machine with asynchronous AWS services, look at some scenarios where the processing time can be unpredictable, explain when traditional solutions such as polling (periodically check) fall short, and demonstrate how to implement a generalized callback pattern to handle asynchronous operations into a more manageable synchronous flow. We cover the related architecture, technical implementation, and best practices, and we provide a real-world examples that uses the AWS Cloud Development Kit (AWS CDK). Services used in this generalized callback pattern include Amazon DynamoDB, Amazon EventBridge and AWS Step Functions.

Understanding the issue this solution addresses

Asynchronous operations are designed to handle long-running operations without blocking resources, a design followed by many AWS services. However, these services create challenges in Step Functions workflows by returning immediate 200 OK responses rather than confirming task completion. This breaks the Step Functions execution model, which expects each step to be complete before advancing. Developers often attempt to address this issue through polling loops to repeatedly check the status of operations, an approach that works for containerized applications and Amazon Elastic Compute Cloud (Amazon EC2). For these services, compute resources are already provisioned, but compute resources become problematic in serverless architectures when AWS Lambda functions have a 15-minute execution limit, making them unsuitable for long-running polls.

Step Functions supports Run a Job (.sync) to call a service and have Step Functions wait for a job to complete, but this works only for selected optimized integrations. However, this functionality is limited to specific AWS services such as AWS Glue. Amazon Translate, Macie, and other services are not optimized integrations. If your operation is not listed as working with .sync, it can benefit from the generalized callback pattern covered in this post.

For these non-optimized integrations, an option is to use polling (periodically check). However, polling can lead to additional latency in response because polling times are unlikely to align with job completion. This is shown in the following figure.

Timeline diagram showing alternating 'Job' blocks and 'Delay' blocks, with 'Poll' markers indicated at regular intervals along the time axis. The diagram illustrates a sequential process of job execution and delay periods.

Figure 1: A job processing and delay timeline diagram

The Step Functions generalized callback pattern can solve this latency issue by pausing execution for up to one year while waiting for task completion (this does not incur additional cost). When such an asynchronous operation finishes, a callback mechanism resumes the workflow where it left off. This generalized callback pattern transforms asynchronous operations into synchronous ones, and it maintains cost efficiency and operational agility.

Scenarios

To help us see where this generalized callback pattern could be applied, let’s look at a few scenarios. Each of these scenarios makes use of AWS Step Functions state machines to run the applications’ workflows.

Scenario 1: Document translation with personally identifiable information compliance

Organizations must manage personally identifiable information (PII) when translating documents because PII can be duplicated across language outputs. For example, when translating a document containing “Jane Doe,” that name appears in both the original and translated versions, creating multiple instances of sensitive data that need compliance measures. Amazon Translate batch translation has a default concurrency of 10, meaning that translations could take more than 10 minutes or be queued for longer periods. Additionally, the Amazon Translate batch translation operation is asynchronous, holding the translation request in a queue until completed. The generalized callback pattern in this post makes sure that Step Functions state machine workflows resume appropriately to apply consistent PII handling across all outputs. In this scenario the design makes use of tagging Amazon Simple Storage Service (Amazon S3) files as containing PII or not, which in turn associates S3 lifecycle policies for specific retention periods to those S3 objects.

Workflow diagram showing five connected steps: 1) Start, 2) StartTextTranslationJob, 3) Wait for Translate result, 4) Tag all files, 5) ending with End state.

Figure 2: A text translation workflow diagram

Scenario 2: Using concurrent execution to pause the state machine until processes have completed

Continuing from scenario 1, Macie and Amazon Translate can run in parallel (each approximately 10 minutes) rather than sequentially (approximately 20 minutes) for a better user experience. Similarly to Amazon Translate batch translation operations being asynchronous, the Macie create classification operation is also asynchronous. Step Functions state machines enable concurrent execution of both service requests. The generalized callback pattern enables the state machine to pause each parallel workflow and resume only when the asynchronous services have completed their jobs. Without this pattern, both services would immediately return 200 OK responses, causing the workflow to continue prematurely before translations or classification results are available. If the classification results are not available later in the workflow, then the appropriate PII tags will not be applied and therefore the appropriate lifecycle retention policy will also not be applied, resulting in not adhering to PII handling practices.

Figure 3: A parallel classification and translation workflow diagram

Scenario 3: Intelligent document processing

Organizations that use Bedrock Data Automation for intelligent document processing must take into consideration Regional concurrency limits. BDA has Regional concurrency limits “Max number of concurrent jobs” of 25 jobs in the us-east-1 and us-west-2 Regions. Also, BDA has a concurrency limit of only five jobs in other supported Regions, so large document batches could be queued for extended periods resulting in long processing wait times for the user. This service functionality is handled asynchronously as the duration of the request could be many minutes. The generalized callback pattern makes sure that workflows resume appropriately as soon as a job finishes rather than waiting an arbitrary time to check if the job has been completed. For example, the generalized callback pattern for BDA can be used to enhance the solution outlined in the blog post, Scalable intelligent document processing using Amazon Bedrock Data Automation.

Figure 4: A data automation workflow diagram

Solution architecture

The following architecture diagram shows the generalized callback pattern (the blue section on the right side) integrated with your existing application (the grey section on the left side).

Figure 5: The Step Functions generalized callback architecture

Key components of this post’s solution architecture

This generalized callback pattern architecture consists of four essential components working together. Each component plays a specific role while maintaining cost efficiency and operational reliability. The following components form the foundation of this pattern:

  • Step Functions task: Implements the “Wait for Callback” task state generating unique task tokens for workflow resumption.
  • EventBridge rule: Monitors asynchronous service completion events and is customizable for different service patterns. AWS services make use of an event bus to route service event notifications to other services, such as job completions.
  • DynamoDB: Provides persistent storage correlating job IDs with task tokens for quick lookup.
  • Step Functions state machine: Manages the resume process and makes sure of proper cleanup of stored tokens.

Solution process

This generalized callback pattern operates through a coordinated sequence of four key steps. Each step builds upon the previous one. The following process demonstrates how the pattern manages workflow execution. The diagram above shows more detailed steps following these key steps.

  1. Start the asynchronous operation for which you want to wait for completion. The asynchronous service responds with success (200 OK) and the state machine continues. Initiating an Amazon Translate batch translation operation is one example of such an asynchronous operation.
  2. Trigger the generalized callback pattern with the “Wait for Callback” capability. Pair the task token with the jobId in DynamoDB using the unique jobId as the primary key. Example:
    {
        id    = translationJobId,
        token = stepFunctionTaskToken
    }
  3. Monitor for completion: When the asynchronous service completes the requested job, such as translation of documents, an event is created in EventBridge that contains the jobId and status. Example:
    {
        jobId  = translationJobId,
        status = complete
    }
    
  4. Resume workflow: The EventBridge rule triggers the workflow to resume, which looks up the task token using the jobId, resumes the paused Step Functions execution, and cleans up the database entry.

Not every service creates events for every action, so validate that your service operation generates the expected events. For example, Macie does not create events when no findings are discovered. In these cases, implement more event generation mechanisms through Amazon CloudWatch Logs subscriptions that trigger Lambda functions to create custom events.

Technical implementation of the solution

For rapid deployment of this post’s solution, AWS CDK users can use this sample CDK pattern with all key components. Alternatively, you can implement the individual components yourself by using the following steps, with each component customizable to your requirements.

Some of the JSON-based snippets below are Amazon States Language (ASL) snippets, which is the language that defines an AWS Step Functions state machine. State machines can be built in the AWS Console using the drag and drop visual builder, or with ASL. The visual builder generates this ASL and you can toggle to view/edit the workflow code (ASL).

Use a Step Functions task that supports “WaitForCallback” to store task token in DynamoDB

Use a Step Functions task that supports ”WaitForCallback” to store the task token in DynamoDB alongside the job ID from the asynchronous service.

AWS services generate a unique ID for that service which refers to that job/request/action. DynamoDB holds the mappings between job IDs and task tokens, supporting multiple state machines paused in parallel with concurrent execution. To prevent clashes when different asynchronous services generate overlapping IDs (for example, if Service A and Service B both generate ID “12345”), use separate DynamoDB tables for each service to maintain ID uniqueness. The sample AWS CDK pattern demonstrates this approach by providing dedicated DynamoDB tables and Step Functions state machines for each service integration. This ID-token structure allows for quick lookups for workflow resumption and cleanup.

The following ASL accomplishes this by using a DynamoDB PutItem task:

"DynamoDB PutItem": {
    "Type": "Task",
    "Resource": "arn:aws:states:::dynamodb:putItem",
    "Parameters": {
        "TableName": "resumeTokenSessionTable",
        "Item": {
            "id":    { "S.$": "$.JobId" },
            "token": { "S.$": "$$.Task.Token" },
            "ttl":   { "S.$": "$.ttl" }
        },
        "ConditionExpression": "attribute_not_exists(id)"
    },
    "Next": "XXXX"
}

In this example, the Item object stores three values: the job ID ($.JobId), the task token ($$.Task.Token), and a TTL value ($.ttl). The ttl field configures Time to Live for automatic cleanup based on your service’s expected completion time. Since this stores only three small string values, data usage per entry is minimal. The primary consideration is the number of concurrent operations, as each active asynchronous job requires one DynamoDB entry until completion or TTL expiration.

The DynamoDB table uses “id” as the primary key and includes a “token” attribute. These fields are essential for the “WaitForCallback” pattern: the “id” (job ID) allows your asynchronous service to look up the correct entry, while the “token” (Step Functions task token) is what your service sends back to Step Functions to resume the paused workflow. The following JSON shows an example of these values:

{
    "id":    { "S": "xxxxxxxx-yyyy-zzzz-aaaa-bbbbbbbbbbbb" },
    "token": { "S": "11111111-2222-3333-4444-555555555555" },
    "ttl":   { "S": "1480550400" }
}

When your asynchronous service completes its work, it retrieves the task token using the job ID, then calls Step Functions with that token to resume execution from where it paused.

The task token acts as a unique identifier for resuming execution at the exact pause point. To prevent overriding an existing record when a duplicate id is used, you can specify a “ConditionExpression”. This ASL shows just the ConditionExpression.

“ConditionExpression”: “attribute_not_exists(id)”

Create an EventBridge rule to monitor event patterns from your asynchronous service

EventBridge integration forms the heart of the event-driven resumption mechanism. You can create EventBridge rules to monitor specific event patterns from asynchronous AWS services. Most AWS services automatically publish completion events to default EventBridge at no cost, and you can use the EventBridge rule wizard to identify correct event patterns. For services that do not publish events—such as Macie that creates no events when no findings are discovered—implement shims by using Amazon CloudWatch Logs to trigger Lambda functions that generate custom events. This JSON shows the EventBridge Rule pattern definition.

"EventPattern": {
    "source": [
        "aws.translate"
    ],
    "detail-type": [
        "Translate TextTranslationJob State Change"
    ],
    "detail": {
        "jobStatus": [
            "COMPLETED"
        ],
    }
}

Resume the workflow

At this point, you know the operation has completed, so you can safely resume the workflow. Using the job ID, call the DynamoDB GetItem operation to receive the task token. This ASL shows the task definition to get the task token for a given job ID retrieved from the event notification.

"getResumeToken": {
    "Next": "sendTaskSuccess",
    "Type": "Task",
    "ResultPath": "$.getResumeToken",
    "Resource": "arn:aws:states:::dynamodb:getItem",
    "Parameters": {
        "Key": {
            "id": { "S.$": "$.id" }
        },
        "TableName": "resumeTokenSessionTable"
    }
}

Use the task token to resume the workflow and then delete the DynamoDB entry for cleanup. This ASL shows the task definition to use the task token to resume the state machine at the point where it was paused at.

"sendTaskSuccess": {
    "Next": "deleteResumeToken",
    "Type": "Task",
    "ResultPath": "$.sendTaskSuccess",
    "Resource": "arn:aws:states:::aws-sdk:sfn:sendTaskSuccess",
    "Parameters": {
        "TaskToken.$": "$.getResumeToken.Item.token.S",
        "Output": {
            "status": "resume"
        }
    }
}

This ASL shows the task definition to clean up the DynamoDB to remove the used task token.

"deleteResumeToken": {
    "End": true,
    "Type": "Task",
    "Resource": "arn:aws:states:::dynamodb:deleteItem",
    "Parameters": {
        "Key": {
            "id": { "S.$": "$.id" }
        },
        "TableName": "resumeTokenSessionTable"
    }
}

This completes the technical implementation of our solution. With all components in place—the WaitForCallback task, EventBridge rules, workflow resumption logic, and DynamoDB storage—you now have a fully functional generalized callback pattern implementation that eliminates polling and efficiently manages asynchronous operations.

Now that we’ve established how to implement the generalized callback pattern technically, let’s explore the best practices and important considerations that will help you optimize and secure your implementation.

Best practices and considerations

When implementing the generalized callback pattern in AWS Step Functions, it’s essential to understand and apply best practices that optimize costs, enhance security, and ensure efficient operation. This section outlines key considerations and recommendations for implementing the pattern effectively, focusing on cost optimization strategies and security measures that help maintain a robust and secure serverless workflow. By following these guidelines, you can maximise the benefits of the generalized callback pattern while minimising potential risks and unnecessary expenses.

Optimize costs by using this post’s generalized callback pattern

Managing costs for long-running asynchronous operations can present challenges. Traditional polling accumulates unnecessary expenses through repeated state transitions and execution time, but this post’s generalized callback pattern is an event-driven approach that significantly reduces operational costs.

Eliminate polling costs and minimize execution time

The generalized callback pattern reduces costs by eliminating polling transitions and pausing execution during wait periods. For standard workflows billed at $0.000025 per state transition, using just two transitions instead of continuous polling achieves approximately an 87% cost reduction. A 15-minute translation job polling every minute would need 15 transitions as opposed to two with the generalized callback pattern. For express workflows billed at $0.000001 per request and $0.00001667 per GB-second, the pattern delivers significant savings through reduced request count and minimal execution time. Traditional polling keeps workflows active during the entire operation, accumulating execution time charges. By contrast, the generalized callback pattern eliminates execution time charges during the wait period. In the translation job example mentioned previously in this paragraph, this could reduce the execution time from more than 15 minutes to just the seconds needed to start jobs and complete processes.

Increase resource efficiency

The callback pattern increases resource efficiency by removing constant polling, resulting in substantial reduction in CloudWatch logging and associated monitoring costs. This creates a more cost-effective solution with a reduced AWS resource footprint.

Further cost-optimize the callback pattern

Enhance cost efficiency through DynamoDB optimizations. Choose on-demand mode for unpredictable workloads or provisioned mode with auto scaling for consistent patterns, configure auto scaling settings based on usage, and implement TTL to automatically remove expired items without consuming write capacity.

Security considerations for the callback pattern

The callback pattern involves storing task tokens, processing events, and managing workflow resumption across multiple AWS services. Implementing proper access controls is essential to protect the integrity of your workflows and prevent unauthorized access or manipulation of the pattern’s components.

This section outlines the security considerations for the callback pattern, focusing on access controls for data storage and event processing.

Data storage security

Enable DynamoDB encryption at rest by using AWS owned or user managed AWS Key Management Service (AWS KMS) keys. Implement identity-based policies by defining the Step Functions AWS Identity and Access Management (IAM) role actions (such as PutItem, GetItem, and DeleteItem) and resource-based policies that specify which IAM principals can access the table. Together, these help ensure that only authorized state machines access token storage and operations are limited to minimum permissions. Also, configure TTL to automatically remove expired tokens so that these tokens do not accidentally get reused, which can result in errors with resuming the relevant AWS Step Function workflows.

Event processing security

Scope EventBridge rules precisely to match only specific necessary events. For Amazon Translate job completion, rules should explicitly match only translation job completion events, thus preventing unauthorized triggers. IAM roles should follow least-privilege principles so that only specific actions can cause workflows to resume.

Conclusion

The callback pattern presented in this post provides a solution for managing long-running asynchronous operations in serverless architectures. You can use the Step Functions “Wait for Callback” task state with EventBridge and DynamoDB to transform asynchronous services into synchronous workflows without the overhead of polling. This pattern reduces costs, improves efficiency through event-driven architecture, and maintains security through proper access controls. You can use the provided CDK implementation to implement this pattern and adapt it to your specific needs while following recommended security and cost optimization practices. 


About the authors

Maria John is a Senior Solutions Architect at Amazon Web Services, helping customers build solutions on AWS.

Philip Whiteside is a Senior Solutions Architect at Amazon Web Services. Philip is passionate about overcoming barriers by utilizing technology.

Analyzing Amazon EC2 Spot instance interruptions by using event-driven architecture

Post Syndicated from Shekhar Shrinivasan original https://aws.amazon.com/blogs/big-data/analyzing-amazon-ec2-spot-instance-interruptions-by-using-event-driven-architecture/

Amazon Elastic Compute Cloud (Amazon EC2) Spot Instances offer significant cost savings of up to 90% compared to On-Demand pricing, making them attractive for cost-conscious workloads. However, when using Spot Instances within AWS Auto Scaling Groups (ASGs), their unpredictable interruptions create operational challenges. Without proper visibility into interruption patterns, teams struggle to optimize capacity planning, implement effective fallback mechanisms, and make informed decisions about workload placement across availability zones and instance types.

This challenge can be addressed through a custom event-driven monitoring and analytics dashboard that provides near real-time visibility into Spot Instance interruptions specifically for ASG-managed instances. For the remainder of this document, we’ll refer to this custom solution as “Spot Interruption Insights” for Auto Scaling Groups.

In this post, you’ll learn how to build this comprehensive monitoring solution step-by-step. You’ll gain practical experience designing an event-driven pipeline, implementing data processing workflows, and creating insightful dashboards that help you track interruption trends, optimize ASG configurations, and improve the resilience of your Spot Instance workloads.

Solution overview

The architecture uses an event-driven approach utilizing AWS native services for robust spot instance interruption monitoring.

The solution uses Amazon EventBridge to capture interruption events, Amazon Simple Queue Service (Amazon SQS) for reliable message queuing, AWS Lambda for data processing, and Amazon OpenSearch Service for storage and visualization of interruption patterns.

  1. EC2 Spot interruption notices are captured via an Amazon EventBridge rule.
  2. The notices are routed to an SQS queue for reliable message handling.
  3. A Lambda function processes the events, fetching EC2 instance metadata and AWS Auto Scaling Group (ASG) details by making optimized batch calls to the EC2 and Auto Scaling APIs. This design minimizes throttling risks on the control plane APIs, ensuring scalability. The Lambda function is configured with batching and concurrency limits to prevent overwhelming the API endpoints and the OpenSearch Service bulk indexing process.
  4. After processing, events are bulk-indexed into Amazon OpenSearch Service, enabling near real-time visibility and analytics.

A Dead Letter Queue (DLQ) ensures no data is lost in case of failures, while AWS Identity and Access Management (IAM) roles enforce least-privilege access between all components.

The OpenSearch Service domain is deployed within the private subnets of an Amazon VPC, ensuring it is not publicly accessible.

  1. Access to OpenSearch Dashboards is routed through an Application Load Balancer (ALB) configured with an HTTPS listener,
  2. ALB forwards traffic to an NGINX proxy running on EC2 instances in an Auto Scaling group. This setup provides secure and scalable access.
  3. Authentication and authorization are enforced using OpenSearch Service’s internal user database, ensuring that only authorized users can access the dashboards.

OpenSearch Dashboards visualize interruption metrics, delivering actionable insights to support effective capacity planning and workload placement.

Extensibility and alternative analytics tools

While this solution uses Amazon OpenSearch Service for storing and visualizing Spot Interruption data, the architecture is flexible and can be extended to support other analytics and observability platforms. You can modify the Lambda function to forward data to tools such as Amazon Quick Sight, Amazon Timestream, Amazon Redshift, or external services depending on your analytics and compliance needs. This enables teams to use their preferred tooling for building visualizations, setting alerts, or integrating with existing dashboards.

What you’ll build

By the end of this post, you’ll have a complete Spot Interruption monitoring system as seen in the following screenshot that automatically captures EC2 Spot Instance interruption events from your Auto Scaling Groups and presents them through interactive dashboards. Your solution will include real-time visualizations showing interruption patterns by availability zone, instance types, and time periods, along with ASG-specific metrics that help you identify optimization opportunities.

The sections of this post walk you through the step-by-step implementation of this solution, from deployment to setting up the event-driven architecture to configuring the analytics dashboards. Remember that you can deploy and customize this solution for your environment.

Prerequisites

You must have access to an AWS account with enough privileges to create and manage the AWS resources discussed in this blog post.You must also have the following software/components installed on your device:

Note: This application utilizes multiple AWS services, and there are associated costs beyond the Free Tier usage. Refer to the AWS Pricing page for specific details. You are accountable for any incurred AWS costs. This example solution does not imply any warranty.

Deployment instructions

Create a new directory, navigate to that directory in a terminal and clone the GitHub repository:

git clone https://github.com/aws-samples/sample-spot-interruption-insights

Change directory to the solution directory:

cd sample-spot-interruption-insights

Checklist for deployment

This section lists the setup and configurations that are required before you deploy the solution stack by using AWS SAM.

If you don’t have a VPC, Subnets, NAT Gateway already created and configured you can follow the steps mentioned in the Amazon VPC documentation to create the necessary resources.

  1. VPC Created – Ensure a VPC exists with DNS hostnames and DNS resolution enabled. You will need the VPC ID during deployment
  2. Public Subnets (2 or more) – Configure two or more public subnet IDs from different Availability Zones.
  3. Private Subnets (2 or more) – Configure two or more private subnet IDs from different Availability Zones.
  4. Outbound Internet Access for Private Subnets – Ensure NAT Gateway access as nginx proxy will be installed on EC2 instance in private subnet. Refer to Example: VPC with servers in private subnets and NAT for more information on setting up NAT for instances in private subnets.
  5. ALB Access – CIDR IP range allowed to access ALB (such as, `1.2.3.4/32`). This is for accessing the dashboard.
  6. Certificate ARN for ALB HTTPS Listener – To configure HTTPS listener. Certificate (can be self-signed) for HTTPS port of the load balancer. Refer to Prerequisites for importing ACM certificates for more information on importing self-signed certificate into AWS Certificate Manager (ACM)
  7. OpenSearch Service-Linked Role – Before deploying this template, ensure the AWS OpenSearch service-linked role exists in your account by running:
    aws iam create-service-linked-role --aws-service-name es.amazonaws.com

    Note:

    • This command only needs to be run once per AWS account.
    • If the role already exists, you’ll see an error message that can be safely ignored.
    • This role allows Amazon OpenSearch Service to manage network interfaces in your VPC.
    • Without this role, deployments that place OpenSearch Service domains in a VPC will fail with the error: “Before you can proceed, you must enable a service-linked role to give Amazon OpenSearch Service permissions to access your VPC.”
    • The service-linked role is named "AWSServiceRoleForAmazonOpenSearchService" and is managed by AWS.
  8. AMIId – Valid EC2 AMI ID for the region. Note:- This solution is designed to work exclusively with AMIs that use the DNF package manager. Use the latest Amazon Linux 2023 AMI for optimal compatibility and security.

    The following AMIs are confirmed compatible with this solution:

    • Amazon Linux 2023
    • Fedora (35 and newer)
    • RHEL 8 and newer
    • CentOS Stream 8 and newer
    • Oracle Linux 8 and newer

Build and deploy the solution – From the command line, use AWS SAM to build and deploy the AWS resources as specified in the template.yml file.

sam build
sam deploy --guided

During the prompts: Fill-out the following parameters:

  • Stack Name: {Enter your preferred stack name}
  • AWS Region: {Enter your preferred region code}
  • Parameter DomainName: {Enter the name for your new OpenSearch Service domain where the index will be created and data will be pushed for analytics. This will create a new OpenSearch domain with the name you specify – Preferably keep short domain name}
  • MasterUsername: {Admin username to login to the OpenSearch dashboard}
  • MasterUserPassword: { Must contain lowercase, uppercase, numbers, and special characters (!@#$%^&*). Minimum 12 characters recommended. Avoid common passwords (Password123!, Admin@2024 and more) as these may cause deployment failures due to security validation checks.}
  • IndexName: {OpenSearch Index name where Spot interrupted instance related data will be pushed}
  • EventRuleName: {Amazon EventBridge rule name to capture EC2 Spot interruption notices}
  • CustomEventRuleName: {Amazon EventBridge custom rule name to capture EC2 Spot interruption notices. This will be used for verifying the solution}
  • TargetQueueName: {EventBridge Rule target SQS name}
  • SQSDLQQueueName: {Target SQS Dead Letter Queue name}
  • LambdaDLQQueueName: {Lambda Dead Letter Queue name}
  • VPCId: {Enter the VPCId where the resources will be deployed}
  • PublicSubnetIds: {Enter 2 or more Public SubnetIDs separated by comma}
  • PrivateSubnetIds: {Enter 2 or more Private SubnetIDs separated by comma}
  • RestrictedIPCidr: {IP address/CIDR for restricting ALB access in CIDR format (such as 10.2.3.4/32)}
  • CertificateArn: {Certificate ARN for configuring ALB HTTPS Listener}
  • AMIId: {Valid EC2 AMI ID for the region}
  • Confirm changes before deploy: Y
  • Allow SAM CLI IAM role creation: Y
  • Disable rollback: N
  • Save arguments to configuration file: Y
  • SAM configuration file: {Press enter to use default name}
  • SAM configuration environment: {Press enter to use default name}

Note: The complete solution may take approximately 15-20 minutes to deploy. After the deployment is complete, there are a few manual steps that need to be performed to ensure the solution functions as expected.

Post deployment instructions

The following steps need to be performed in OpenSearch Dashboards after logging in. Get the DNS Name of the Application Load Balancer endpoint from the deployment output section of the CloudFormation stack or the ALB console. Access the OpenSearch dashboards using the ALB DNS name as follows –

https://[ALB-DNS-NAME]/_dashboards

You will be redirected to the OpenSearch Dashboards login page. Log in using the MasterUsername and MasterUserPassword you specified during deployment.

If this is the first time you are logging in then you may see a Welcome screen.

  1. Choose ‘Explore on my own’ on the Welcome screen.
  2. Choose ‘Dismiss’ on the next screen.
  3. If the ‘Select your tenant’ dialog appears with ‘Global’ preselected, Choose ‘Confirm’. Otherwise, select ‘Global’ first and then and choose ‘Confirm’.

Create index and attribute mapping

This section lists the required steps to create the index and attribute mapping.

  1. On the Home screen select the Hamburger Menu icon () on the top left
  2. Select ‘Dev Tools’ at the bottom of the menu.
  3. On the dev tools console, paste the following PUT command and execute the request by choosing ‘Click to send request’.

    Note The index name should match what you entered during the deployment. Change the index name accordingly before creating the index.

    PUT /<YOUR-INDEX-NAME-SPECIFIED-DURING-DEPLOYMENT>
            {
                "mappings": {
                    "properties": {
                    "instance_id": {
                        "type": "keyword"
                    },
                    "instance_name": {
                        "type": "keyword"
                    },
                    "instance_type": {
                        "type": "keyword"
                    },
                    "asg_name": {
                        "type": "keyword"
                    },
                    "timestamp": {
                        "type": "date"
                    },
                    "region": {
                        "type": "keyword"
                    },
                    "availability_zone": {
                        "type": "keyword"
                    },
                    "private_ip": {
                        "type": "ip"
                    },
                    "public_ip": {
                        "type": "ip"
                    }
                    }
                }
            }

    The following is a screenshot of this command in Dev Tools.

  4. Confirm that the index was created successfully.

Create index pattern

This section lists the required steps to create the index pattern

  1. Access the Hamburger Menu icon on the top left.
  2. Select ‘Dashboard Management’ from the bottom of the menu.
  3. Choose ‘Index Patterns’
  4. Choose “Create Index Pattern”
  5. Enter the Index pattern name and choose “Next step”.
    The index pattern name should be the index name you entered during the deployment followed by an asterisk. See the following screenshot for reference.

  6. Select ‘timestamp’ in primary Time field and choose ‘Create index pattern’
  7. Choose the star icon to make the index pattern default

Configure Lambda with required access for new index

In this section you will create a role in OpenSearch Service dashboards and will map Lambda execution role to the same to perform operations on the new index.

  1. Navigate to the Lambda console
  2. Search for the function beginning with your OpenSearch Service domain name.
  3. In the function details, go to Configuration > Permissions
  4. Choose the Role Name in the Execution Role section.
  5. Copy the Lambda execution role ARN from this function which handles Spot interruption events.
  6. Access the Hamburger Menu icon on the top left and select ‘Security’ from the bottom of the menu.
  7. Now select the ‘Roles’ menu option under ‘Security’ menu and then select ‘Create Role’
    • Enter a role name and set Cluster Permissions to “cluster_composite_ops_ro“.
    • For Index Permissions, select the index pattern name created during deployment.

    See the following screenshot for reference.

  8. Set the Tenant Permissions to “global_tenant” as seen in the image and Choose “Create”.

  9. After the role is created, on the same screen, select the ‘Mapped Users’ tab and choose ‘Manage Mapping’

  10. Choose ‘Manage Mapping’
  11. In the ‘Backend roles’ add the Lambda execution role ARN copied earlier and Choose ‘Map’

You can create more users in the internal database and grant appropriate access to the visualisations and dashboards. The following steps show how to create a read only role and to create an internal user and grant read only access.

Manage users and roles

In this section you will create a new user and a role with read-only access, then assign the role to the user to grant them read-only access to the Spot Interruption dashboard and visualizations.

  1. Access the Hamburger Menu icon on the top left
  2. Select ‘Security’ from the bottom of the menu
  3. Select ‘Internal Users’ and then select ‘Create Internal user’
  4. Enter username and set a Password, then choose “Create”.

  5. Now select the ‘Roles’ menu option under ‘Security’ menu and then select ‘Create Role’
    • Enter the role name and set Cluster Permissions to “cluster_composite_ops_ro“.
    • For Index Permissions, select the index pattern name created during deployment.

    See the following screenshot for reference.

  6. Set the Tenant Permissions to “global_tenant” as seen in the image and Choose “Create”.

  7. After the role is created, on the same screen, select the ‘Mapped Users’ tab and choose ‘Manage Mapping’

  8. Select the user created above in ‘Users’ and choose ‘Map’

Configure and deploy sample visualisations and dashboard

Sample visualizations and a starter dashboard are provided under the data folder of the git repo you cloned earlier. Look for the file named spot-interruption-dashboard-visualisations.ndjson.To import the visualizations:

  1. Navigate to Saved Objects under Dashboard Management in OpenSearch Dashboards.
  2. Import the spot-interruption-dashboard-visualisations.ndjson file.
  3. During the import, you may encounter index pattern conflicts. Select the index pattern you created from the dropdown and choose “Confirm all changes”.

Once imported, the sample visualizations and dashboard linked to your index pattern will be available under Dashboards in the left-side hamburger menu. You can view the Spot Interruption Dashboard, which includes visualizations based on Availability Zones, Regions, Instance Types, Auto Scaling Groups (ASGs), and Interruptions over time. You can further customize by creating your own visualizations using the attributes available in the index or by editing/creating new dashboards. The dashboard will display empty views until Spot interruption data is available to visualize.

Test the solution

A temporary event rule was created during deployment to simulate matching Amazon EC2 Spot interruption notices. The rule name is the name you specified during deployment for the CustomEventRuleName parameter.

To verify the solution, you can send sample events from the EventBridge console as depicted below. In the AWS console,

  • Open the Amazon EventBridge console
  • In the left menu under ‘Buses’ section choose ‘Event buses’
  • Choose the ‘default’ event bus
  • Choose the ‘Send events’ button
  • In the Send events page enter the following details:
    • Event bus: default
    • Event source: custom.spot.interruption.simulator
    • Detail type: EC2 Spot Instance Interruption Warning
    • Event detail: {"instance-id": "<instance-id>", "Instance-action": "terminate"}

    Replace the instance-id with an actual instance id that is associated with an Amazon EC2 Auto Scaling group. Refer to the following screenshot.

After the event is sent successfully, you can log in to OpenSearch Dashboards and view the Spot Interruption Dashboard, which has been prebuilt with the indexed event data. This dashboard provides insights across key dimensions such as Availability Zones, Regions, instance types, Auto Scaling groups, and interruption trends over time. Use the dashboard as a starting point to understand the kinds of insights possible and customize or create new visualizations based on your needs and the fields available in the index.

Alternatively, you can navigate to the Discover section in the menu to view the raw event details. Ensure that you select the index pattern you created earlier in this demonstration, and adjust the time range if necessary (such as the last 15 minutes) to view the latest data.

Security and cost optimizations

This solution is designed to be secure and cost-efficient by default, but there are some more optimizations you can apply to further reduce cost and enhance security:

Security best practices

  1. Amazon Cognito Authentication : Integrate Amazon Cognito with OpenSearch Dashboards to manage user authentication, enable Multi Factor Authentication, and avoid hardcoding admin credentials. More information Configuring Amazon Cognito authentication for OpenSearch Dashboards
  2. Lambda Layer Versioning: Ensure pinned versions of Lambda Layers are used to avoid unexpected changes. More information Managing Lambda dependencies with layers
  3. Logging and Threat Detection: Enable AWS CloudTrail and Amazon GuardDuty to monitor for unauthorized activity or anomalies. More information Monitoring Amazon OpenSearch Service API calls with AWS CloudTrail

Cost optimizations

  1. Bulk Indexing with Throttling Controls: Lambda processes batches and respects throttling limits to avoid excessive OpenSearch usage.
  2. Short Retention for CloudWatch Logs: Tune log retention periods to avoid unnecessary storage costs.
  3. Optimize Visualizations: Design saved visualizations to avoid expensive queries (like wide time ranges and large aggregations). More information Optimizing query performance for Amazon OpenSearch Service data sources
  4. Index State Management (ISM) : Configure ISM policies in OpenSearch to delete or archive older interruption data. More information Index State Management in Amazon OpenSearch Service

Cleanup

Run the following command to delete the resources deployed earlier.

sam delete

After deleting the stack, make sure to also remove any post-deployment configurations you may have created within the OpenSearch Service dashboards console. While these configurations won’t incur additional costs, it’s considered a best practice to clean up your environment by deleting any resources that are no longer needed. Take some time to review the OpenSearch Service dashboards and identify any custom settings, dashboards, or visualizations you set up during the deployment process. Then, delete these individual configurations to ensure your environment is fully cleaned up.

Conclusion

In this post, you learned how to build and deploy a comprehensive Spot Instance interruption monitoring solution for Auto Scaling groups by using EventBridge, Amazon SQS, Lambda, and OpenSearch Service. You implemented an event-driven pipeline to capture and process Amazon EC2 Spot Instance interruption events, created secure analytics dashboards, and established real-time visibility into interruption patterns across your Auto Scaling group–managed workloads.

This post’s solution empowers your teams with the visibility and agility needed to operate confidently with Amazon EC2 Spot Instances. By combining event-driven architecture with secure, scalable analytics, you can now proactively monitor interruption events, identify interruption trends, and optimize workload strategies for resilience and cost-efficiency.

With real-time data at your fingertips, you’re equipped to make smarter infrastructure decisions and maximize the benefits of Spot Instance capacity while minimizing disruption risks.


About the author

Shekhar Shrinivasan

Shekhar Shrinivasan

Shekhar is a Senior Technical consultant who specializes in cloud architecture design, migration strategies, and AWS workload optimization. He helps enterprise customers accelerate their digital transformation through best practices implementation, scalable infrastructure solutions, and strategic technical guidance to maximize their cloud return on investment.

AWS Lambda networking over IPv6

Post Syndicated from John Lee original https://aws.amazon.com/blogs/compute/aws-lambda-networking-over-ipv6/

IPv4 address exhaustion is a challenge in modern networking, as most IPv4 addresses have been depleted with the growth of the internet. Previously, AWS Lambda only supported inbound and outbound connectivity over IPv4, but it has since introduced support for dual-stack endpoints, so that you can transition from IPv4 to IPv6. AWS continues to add support for IPv6, recently announcing support for inbound IPv6 connectivity over AWS PrivateLink, and dual-stack endpoint support for Amazon API Gateway.

With these IPv6 capabilities now available in Lambda, you should understand how to use them effectively. This post examines the benefits of transitioning Lambda functions to IPv6, provides practical guidance for implementing dual-stack support in your Lambda environment, and considerations for maintaining compatibility with existing systems during migration.

Benefits of transitioning

You can transition to IPv6 to future-proof your overall architecture by preparing ahead of the broader transition to IPv6, and establish compatibility with IPv6 clients or services. IPv6 also eliminates the need for a NAT gateway when the Lambda functions need internet connectivity from a private subnet in your Amazon Virtual Private Cloud (Amazon VPC). Lambda functions can direct traffic to the egress-only internet gateway, potentially eliminating the NAT gateway and its associated charges and streamlining network design. This transition provides cost savings, as egress-only internet gateways are free to use, as opposed to NAT gateways that incurs an hourly charge. Furthermore, IPv6 offers improved network efficiency by eliminating NAT translation overhead, so that Lambda functions can establish direct connections with clients. IPv6 also has more advantages such as native Quality of Service (QoS), which streamlines header structure and reduces packet fragmentations.

Architectural implications

Lambda functions are often deployed inside of a VPC to access VPC resources. For VPC Lambda functions to access the internet, routing traffic through an NAT gateway is a common approach. For Lambda functions with IPv6 support, Lambda functions can now route traffic directly through the egress-only internet gateway, which eliminates the need for a NAT gateway and the extra hop, as shown in the following figures.

architecture diagram showing egress traffic in both ipv4 and ipv6 environments

Figure 1. Lambda internet connectivity through a NAT Gateway (IPv4) and Lambda internet connectivity through an egress-only internet gateway (IPv6).

Once the egress-only internet gateway is in place, you need to update the route table to reflect this. If you have used 0.0.0.0/0 as the default route for IPv4 traffic, you should add ::/0 as the default route for IPv6 traffic. The following image shows the updated route table.

ipv4 and ipv6 route tables

Figure 2. Lambda private subnet routing tables for an NAT Gateway (IPv4) as opposed to a dual-stack including an egress-only internet gateway (IPv6)

If you are using Lambda function URLs, no transition is needed. Lambda function URLs are inherently IPv6-capable and can be accessed by IPv6 clients without needing architectural changes or modifications. This IPv6 compatibility for function URLs operates independently of your Lambda function’s VPC configuration, and clients can reach your Lambda function URLs over IPv6 even when dual-stack is not enabled in your VPC.

For Lambda functions that interact exclusively with AWS services through internal traffic, IPv6 offers limited benefits. For example, in an architecture where a Lambda function processes requests from Amazon API Gateway and queries a database hosted on Amazon Relational Database Service (Amazon RDS), no architectural change is expected. Internal traffic routes using the RDS cluster endpoint and Lambda Amazon Resource Name (ARN), not IP addresses, as shown in the following figure.

architecture diagram showing traffic going through API GW, Lambda, and RDS

Figure 3. A common architecture pattern where Lambda processes events from API Gateway and reads/writes to Amazon RDS. You reference the Lambda function ARN and RDS cluster endpoint instead of IPv4/IPv6 addresses.

Transitioning from IPv4 to IPv6

By default, Lambda functions communicate over IPv4 to their destinations. For Lambda functions to communicate with IPv6 destinations, dual-stack VPC configuration is needed. This allows Lambda functions to communicate over both IPv4 and IPv6.

If your VPC does not have IPv6 support, then you need to first add IPv6 support for your VPC. You need to follow these steps to enable IPv6 traffic for a Lambda function:

  1. Assign IPv6 block to VPC: You need to edit the existing VPC CIDRs to add an IPv6 CIDR block. If you select the option of Amazon-provided IPv6 CIDR block, then you are assigned a /56 IPv6 CIDR block from the Amazon pool of IPv6 addresses. You also have the option to assign an Amazon VPC IP Address Manager allocated or your own IPv6 CIDR block.
  2. Assign IPv6 block to Subnets: After assigning an IPv6 CIDR block to the VPC, you must manually configure IPv6 CIDR blocks for each existing subnet, with each subnet receiving a portion of the VPC’s IPv6 address space.
  3. Update route tables: For your Lambda function’s IPv6 traffic to reach the internet, you need to add a route (::/0) to the egress-only internet gateway.
  4. Update security groups: By default, security groups allow all outbound traffic. To restrict outbound IPv6 traffic from your Lambda function, you must remove the default egress rule and add specific restrictive outbound rules. For inbound traffic, security group rules are needed when your Lambda function receives direct network connections, such as traffic through AWS PrivateLink connections.
  5. Enable IPv6 dual-stack on the Lambda function: When you assign IPv6 addresses for your Lambda function’s subnet, you can enable IPv6 dual-stack for the Lambda function. Then, Lambda creates new Elastic network interfaces (ENI) with IPv4 and IPv6 protocols with both IPv4 and IPv6 addresses. Although most updates to the Lambda function have zero downtime, enabling dual-stack may cause disruption in connectivity. To prevent downtime during the transition, we recommend using Lambda versions and aliases to implement a blue/green deployment strategy. You can publish your IPv6-enabled Lambda function as a new version while keeping the current version active and serve traffic through the alias. After testing the new IPv6 version, you can update the alias to switch the traffic. This approach provides a rollback capability, and you can revert the alias to point back to the previous version if needed.

When you have completed these steps, your Lambda function can support dual-stack networking and communicate over both IPv4 and IPv6.

Conclusion

In this post, we covered the benefits of transitioning your AWS Lambda functions from IPv4 to IPv6, the architectural implications, and steps for how you could make the transition.We recommend transitioning your Lambda functions to support both IPv4 and IPv6 traffic to gain its benefits. The Lambda IPv6 support helps address IPv4 exhaustion while providing cost savings and network clarification. Once organizations transition to supporting only IPv6 traffic, they can eliminate NAT gateways for Lambda functions needing internet access, thus reducing both costs and architectural complexity. As AWS expands IPv6 support across services, transitioning Lambda functions to dual-stack networking positions organizations for long-term compatibility while delivering immediate operational benefits.

For more information on how to enable IPv6 access for Lambda functions in dual-stack VPC, see the Lambda documentation. For more serverless learning resources, visit Serverless Land.

Migrating from Open Policy Agent to Amazon Verified Permissions

Post Syndicated from Samuel Folkes original https://aws.amazon.com/blogs/security/migrating-from-open-policy-agent-to-amazon-verified-permissions/

Application authorization is a critical component of modern software systems, determining what actions users can perform on specific resources. Many organizations have adopted Open Policy Agent (OPA) with its Rego policy language to implement fine-grained authorization controls across their applications and infrastructure. While OPA has proven effective for policy-as-code implementations, organizations are increasingly looking for more performant and managed services that reduce operational overhead while maintaining the flexibility and power of policy-based authorization.

Amazon Verified Permissions is a fully managed authorization service that uses the Cedar policy language to help you implement fine-grained permissions for your applications. Cedar is an open source policy language developed by AWS that provides many of the same capabilities as Rego while offering improved performance (42–60 times faster than Rego), straightforward policy authoring, and formal verification capabilities. By migrating from OPA to Verified Permissions, organizations can reduce the operational burden of managing authorization infrastructure while gaining access to a service designed specifically for scalable, secure authorization.

This migration offers several key benefits: reduced infrastructure management overhead, improved policy performance and validation, enhanced security through the AWS managed service model, and seamless integration with other AWS services. Additionally, Cedar’s syntax is designed to be more intuitive than Rego, reducing the effort needed to write, read, and maintain policies.

In this post, we explore the process of migrating from OPA and Rego to Verified Permissions and Cedar, including policy translation strategies, software development and testing approaches, and deployment considerations. We walk through practical examples that demonstrate how to convert common Rego policies to Cedar policies and integrate Verified Permissions into your existing applications.

Solution overview

The migration from OPA to Verified Permissions represents a shift from self-managed authorization infrastructure to a fully managed service. In a typical OPA setup, customers have OPA servers running either as sidecars, standalone services, or embedded libraries that evaluate Rego policies against incoming authorization requests. These servers pull policy bundles from storage systems and maintain their own performance and availability.

With Verified Permissions, AWS manages the entire authorization infrastructure. Applications make API calls to the Verified Permissions service which evaluates Cedar policies stored in managed policy stores. This removes the need to operate and maintain OPA servers, manage policy distribution, or handle service scaling and availability. This shift means that your team can concentrate on authorization logic rather than infrastructure management while gaining the benefits of the scale and reliability provided by AWS.

Understanding the differences: Comparing Rego with Cedar

It’s important to understand the fundamental differences between the Rego and Cedar policy languages before beginning your migration. These differences will shape how you approach translating your existing policies.

Policy structure and philosophy

Rego policies are built around rules that can be evaluated to produce sets of results. Rego uses a logic programming approach where you define conditions that must be satisfied for a rule to be true. Policies often involve complex queries, loops, and comprehensions to examine data structures.

Example Rego policy

package authz
default allow = false

# Rule 1: Allow users with the viewer role to read documents
allow {
	input.action == "read"
	input.resource.type == "document"
	input.user.role == "viewer"
}
# Rule 2: Allow users with the editor role to write documents
allow {
	input.action == "write"
	input.resource.type == "document"
	input.user.role == "editor"
}

Cedar takes a more declarative approach with explicit permit and forbid statements. Each Cedar policy is a standalone authorization decision that clearly states what is being allowed or denied. Cedar policies are designed to be human-readable and straightforward to audit.

Equivalent Cedar policies

// Policy 1: Allow principals with the viewer role to read documents 
permit (
	principal in UserRole::"viewer",
	action == Action::"read",
	resource in ResourceType::"document"
);
// Policy 2: Allow principals with the editor role to write documents
permit (
	principal in UserRole::"editor",
	action == Action::"write",
	resource in ResourceType::"document"
);

Data model differences

One of the most significant differences between the two evaluation engines is how they handle data. Rego works with arbitrary JSON input data, giving users complete flexibility in how they structure authorization requests. Users can access any field in your input data using Rego’s path notation.

Cedar allows for the creation of a defined schema with typed entities. This means that users need to model authorization data as entities with specific types, attributes, and relationships. While this requires more upfront planning, it provides superior validation, runtime performance, and tooling support.

Policy evaluation

Rego and Cedar differ fundamentally in their approaches to policy evaluation. Rego uses a logic programming model and, as a result, policy evaluation functions much like a logic puzzle solver. It starts with a question and searches backward through linked rules to find an answer. This approach allows for flexible policy composition but can often be slower, less predictable, and more difficult to audit.

Cedar, on the other hand, uses a simpler functional evaluation approach. It uses a straightforward evaluation model where each policy is checked independently against the authorization request. Policies use basic conditional logic to produce fast, deterministic allow or deny decisions. A policy either fully matches the authorization request (principal, action, resource, and all conditions), or it doesn’t apply. This is essential for high-performance authorization scenarios where predictable evaluation time and clear audit trails are essential. Cedar policy evaluation follows four core principles:

  • Default deny for access not explicitly granted
  • Forbid overrides permit for handling policy conflicts
  • Order-independent evaluation to prevent bugs
  • Deterministic outcomes for reliable results

Setting up Verified Permissions

Before you can begin migrating your authorization policies, you need to establish the foundational infrastructure in Verified Permissions.

Creating your policy store

To illustrate the migration process, you will use a fictional document management application that uses OPA and Rego for authorization. The first step in migrating to Verified Permissions is creating a policy store. A policy store is a container for your Cedar policies and schema. You can create multiple policy stores for different applications or environments.

When creating a policy store, you choose between two validation modes:

  • STRICT mode: Requires a schema against which policies are validated
  • OFF mode: Allows policies without a schema (useful for initial testing)

For production migrations, STRICT mode is recommended because it provides better validation compared to OFF mode and can enable optimizations that reduce the entity data needed for authorization requests. You can create a policy store through the AWS Management Console, AWS Command Line Interface (AWS CLI), or programmatically using AWS SDKs. The following example uses the AWS CLI:

aws verifiedpermissions create-policy-store \
	--region us-east-1 \
	--validation-settings mode=STRICT \
	--description "Migration from OPA to Amazon Verified Permissions"

If the request is successful, you should see a JSON encoded response that looks like the following:

{
	"policyStoreId": "PSEXAMPLEabcdefg012345",
	"arn": "arn:aws:verifiedpermissions:us-east-1:123456789012:policy-store/PSEXAMPLEabcdefg012345",
	"createdDate": "2025-09-15T10:30:45.123456+00:00",
	"lastUpdatedDate": "2025-09-15T10:30:45.123456+00:00"
}

Make note of the policyStoreId from the response—you will need it for subsequent operations.

Defining your schema

In STRICT mode, Verified Permissions requires a Cedar schema that defines the types of entities in an authorization system. This schema serves several important purposes, including validating policies at creation time, enabling entity slicing performance optimizations, enabling better tooling and IDE support, and documenting your authorization model. The schema should define:

  • Entity types: The kinds of objects in your system (for example, users, roles, documents, and so on.)
  • Attributes: Properties that entities can have (for example, department, classification, and createdDate)
  • Actions: Operations that can be performed (for example, read, write, and delete)
  • Relationships: How entities relate to each other (for example, user belongs to role, document owned by user)

When designing a schema, you should consider how your current OPA input data maps to Cedar entities. For example, if your Rego policies access input.user.department, you will need a User entity type with a department attribute. The following is an example Cedar schema for your document management application:

{
	"MyApp": {
		"entityTypes": {
			"User": {
				"shape": {
					"type": "Record",
					"attributes": {
						"department": {"type": "String"},
						"jobLevel": {"type": "Long"},
						"email": {"type": "String"}
					}
				}
			},
			"Role": {
				"shape": {
					"type": "Record",
					"attributes": {"name": {"type": "String"}}
				}
			},
			"Document": {
				"shape": {
					"type": "Record",
					"attributes": {
						"owner": {"type": "Entity", "name": "User"},
						"classification": {"type": "String"},
						"createdDate": {"type": "String"}
					}
				}
			}
		},
		"actions": {
			"read": {"appliesTo": {"principalTypes": ["User"], "resourceTypes": ["Document"]}},
			"write": {"appliesTo": {"principalTypes": ["User"], "resourceTypes": ["Document"]}},
			"delete": {"appliesTo": {"principalTypes": ["User"], "resourceTypes": ["Document"]}}
		}
	}
}

To apply this schema to the policy store you created earlier using the AWS CLI, you can run the following command:

aws verifiedpermissions put-schema \
	--region us-east-1 \
	--policy-store-id YOUR_POLICY_STORE_ID \
	--definition file://schema.json

Ensure that you replace YOUR_POLICY_STORE_ID with the policyStoreId that was returned when you created your policy store.

You can view the visualized policy schema (shown in Figure 1) in the Verified Permissions console by going to Policy Store and choosing Schema.

Figure 1: Verified Permissions policy schema visualization

Figure 1: Verified Permissions policy schema visualization

Policy migration patterns

With your policy store and schema in place, you can now begin translating your Rego policies into Cedar policies, following common authorization patterns.

Pattern 1: Role-based access control

Role-based access control (RBAC) is one of the most used authorization patterns. In RBAC systems, users are assigned roles, and roles are granted permissions to perform actions on resources.

In your current Rego implementation, you might check if a user has a specific role in their roles array, then allow certain actions based on that role. Your Rego policy might look something like the following:

package rbac

import future.keywords.if
import future.keywords.in

default allow := false

allow if {
	input.user.roles[_] == "admin"
}

allow if {
	input.user.roles[_] == "editor"
	input.action in ["read", "write"]
}

allow if {
	input.user.roles[_] == "viewer"
	input.action == "read"
}

When migrating to Cedar, you will model this using entity relationships where users belong to role entities.

// Admin users can perform any action on any resource
permit (
	principal in MyApp::Role::"admin",
	action,
	resource
);

// Editor users can read and write on every resource
permit (
	principal in MyApp::Role::"editor",
	action in [MyApp::Action::"read", MyApp::Action::"write"],
	resource
);

// Viewer users can only read on every resource
permit (
	principal in MyApp::Role::"viewer",
	action == MyApp::Action::"read",
	resource
);

Migration approach
To successfully migrate your RBAC policies from Rego to Cedar, follow these steps:

  1. Define User and Role entity types in your schema
  2. Create permit policies for each role-action combination
  3. Use the Cedar in operator to check role membership
  4. Consider creating role hierarchies if you have nested roles

Key differences
Understanding the fundamental differences between Rego and Cedar’s approach to RBAC will help you design more effective policies:

  • Cedar uses entity relationships instead of checking array membership
  • Each permission becomes a separate, explicit policy
  • Role hierarchies are modeled through entity parent-child relationships

Pattern 2: Attribute-based access control

Attribute-based access control (ABAC) makes authorization decisions based on attributes of the user, resource, action, and environment. This is often more flexible than RBAC but can be more complex to implement.

In Rego, you would access various attributes from the input data and use them in policy conditions:

package abac

default allow := false
# Anyone can read public documents
allow if {
	input.action == "read"
	input.resource.classification == "public"
}

# Users can read internal documents from their department
allow if {
	input.action == "read"
	input.resource.classification == "internal"
	input.user.department == input.resource.department
}

# Users can write to documents they own
allow if {
	input.action == "write"
	input.resource.owner == input.user.id
}

Cedar handles this through entity attributes and policy conditions using the when and unless clauses.

// Anyone can read public documents. Blank ‘principal’ and ‘resource’ entities are wildcards that match everything
permit (
	principal,
	action == MyApp::Action::"read",
	resource
) when {
	resource.classification == "public"
};

// Users can read internal documents from their department
permit (
	principal,
	action == MyApp::Action::"read",
	resource
) when {
	resource.classification == "internal" &&
	principal.department == resource.department
};

// Users can write to documents they own
permit (
	principal,
	action == MyApp::Action::"write",
	resource
) when {
	resource.owner == principal
};

Migration approach
Migrating ABAC policies requires careful mapping of attributes from your Rego input structure to Cedar’s entity model:

  1. Identify the attributes used in your current policies
  2. Map these attributes to entity attributes in your Cedar schema
  3. Use when clauses in Cedar policies to implement attribute-based conditions
  4. Consider using context for environment-specific attributes (time, IP address, and so on)

Key differences
Cedar’s schema-driven approach to attributes provides several advantages over Rego’s dynamic attribute access:

  • Cedar requires attributes to be defined in the schema
  • Cedar schema validation helps catch attribute access errors at policy creation time
  • Complex attribute logic might need to be split across multiple policies

Pattern 3: Relationship-based access control

Relationship-based access control (ReBAC) grants permissions based on properties of the resource being accessed or relationships between the user and the resource (such as ownership). In Rego, this might be expressed as follows:

package rebac

import future.keywords.if
import future.keywords.in

# Allow document owners to perform any action
allow if {
	input.resource.type == "document"
	input.resource.owner_id == input.user.id
}

# Alternative: checking ownership through a separate ownership data structure
allow if {
	input.resource.type == "document"
	ownership := data.ownerships[input.resource.id]
	ownership.owner_id == input.user.id
}

In the preceding example, ownership is checked by comparing the owner_id attribute on the resource with the user’s ID. You might access this from the input data directly or from a separate data source. In Cedar, relationships are first-class concepts. The resource.owner == principal syntax directly checks if the principal is the owner entity referenced by the resource. This is more natural and type-safe than string comparisons:

permit (
	principal,
	action,
	resource is MyApp::Document
) when {
	resource.owner == principal
};

Migration approach
Converting relationship-based policies requires modeling your data relationships as Cedar entity references:

  1. Model resources as Cedar entities with relevant attributes
  2. Use resource attributes in policy conditions
  3. Model ownership and other relationships through entity references
  4. Use Cedar’s attribute access syntax for resource properties

Pattern 4: Time and context-based access

Many authorization systems need to consider contextual information such as time of day, user location, or request characteristics (IP address, user-agent, and so on). Expressing this in Rego would look like the following example:

package temporal

import future.keywords.if

default allow := false
# Allow read access during business hours (9 AM to 5 PM UTC)
allow if {
	input.action == "read"
	current_hour := time.clock([time.now_ns(), "UTC"])[0]
	current_hour >= 9
	current_hour <= 17
}

In Cedar, the same policy logic can be expressed like the following:

// Allow read access during business hours (9 AM to 5 PM UTC)
permit (
	principal,
	action == MyApp::Action::"read",
	resource
) when {
	context.currentTime.hour >= 9 &&
	context.currentTime.hour <= 17
};

Migration approach
Context-based policies in Cedar use the context parameter passed with each authorization request:

  • Use Cedar’s context feature for environment information
  • Pass time-based information in the authorization request context
  • Create policies with time-based conditions using context attributes
  • Consider caching implications for time-sensitive policies

Application integration changes

After migrating your policies to Cedar, you need to update your application code to integrate with Verified Permissions.

Updating authorization calls

The most significant change in your application code will be replacing OPA API calls with Verified Permissions API calls. Understanding the differences between these systems will help you plan your integration work effectively. The sample code in this section is written in Python.

Request structure changes

When calling OPA, you typically send a single JSON payload containing the authorization data. For example, your current OPA request might look like the following:

opa_request = {
	"input": {
		"user": {
			"id": "user123",
			"department": "engineering",
			"role": "editor"
		},
		"resource": {
			"id": "doc456",
			"type": "document",
			"owner": "user123"
		},
		"action": "read"
	}
}

response = requests.post(
	"http://opa-server:8181/v1/data/authz/allow",
	json=opa_request
)
authorized = response.json()["result"]

Verified Permissions requires a more structured approach where principals, resources, and actions are explicitly typed entities.

import boto3
import json
from typing import Dict, Any, List

class AuthorizationService:
	def __init__(self, policy_store_id: str, region: str = 'us-east-1'):
		self.client = boto3.client('verifiedpermissions', region_name=region)
		self.policy_store_id = policy_store_id
	
	#Check if a principal is authorized to perform an action on a resource.
	def is_authorized(self, principal: Dict[str, Any], action: str,
				resource: Dict[str, Any], context: Dict[str, Any] = None) -> bool:
		try:
			# Convert to Cedar entity format
			principal_entity = self._to_cedar_entity(principal, "User")
			resource_entity = self._to_cedar_entity(resource, "Document")
			action_entity = {"actionType": "MyApp::Action", "actionId": action}

			request = {
				'policyStoreId': self.policy_store_id,
				'principal': principal_entity,
				'action': action_entity,
				'resource': resource_entity
			}

			if context:
				request['context'] = {'contextMap': context}
				
			response = self.client.is_authorized(**request)
			return response['decision'] == 'ALLOW'
		except Exception as e:
			print(f"Authorization error: {e}")
			return False

	def _to_cedar_entity(self, entity_data: Dict[str, Any], entity_type: str) -> Dict[str, Any]:
		# Convert application data to Cedar entity format
		return {
			'entityType': f'MyApp::{entity_type}',
			'entityId': str(entity_data.get('id', '')),
			'attributes': entity_data
		}

The key differences in this new structure are:

  • Entity type declarations: Each entity (principal, resource) must include an entityType that matches your Cedar schema
  • Entity IDs: Every entity requires a unique entityId for identification
  • Action format: Actions are specified with an actionType and actionId rather than as simple strings
  • Separate context: Environmental information like time, IP address, or user agent is passed in a separate context parameter

Response handling changes

OPA returns whatever your Rego policy outputs, which could be a Boolean, a set of allowed actions, or complex nested data structures. Regardless of the policy outputs, Verified Permissions returns a consistent authorization decision structure:

# Amazon Verified Permissions response structure
{
	'decision': 'ALLOW',# or 'DENY'
	'determiningPolicies': [...],# Which policies determined the decision
	'errors': [...]# Errors that occurred during evaluation
}

Your application logic becomes simpler because you need to check for only ALLOW or DENY:

# Example usage

def check_document_access():
	auth_service = AuthorizationService('YOUR_POLICY_STORE_ID')

	# Example principal (user)
	user = {
		'id': 'user123',
		'department': 'engineering',
		'jobLevel': 5,
		'email': '[email protected]'
	}

	# Example resource (document)
	document = {
		'id': 'doc456',
		'owner': 'user123',
		'classification': 'internal',
		'department': 'engineering'
	}

	# Example context
	context = {
		'currentHour': 14,# 2 PM
		'userAgent': 'MyApp/1.0'
	}

	# Check authorization
	can_read = auth_service.is_authorized(user, 'read', document, context)
	can_write = auth_service.is_authorized(user, 'write', document, context)

	print(f"User can read document: {can_read}")
	print(f"User can write document: {can_write}")

Error handling changes

OPA errors typically relate to policy evaluation issues or server connectivity problems. With Verified Permissions, you’ll encounter AWS-specific error types, as shown in the following example:

def is_authorized_with_error_handling(self, principal, action, resource, context=None):
	try:
		principal_entity = self._to_cedar_entity(principal, "User")
		resource_entity = self._to_cedar_entity(resource, "Document")
		action_entity = {"actionType": "MyApp::Action", "actionId": action}

		request = {
			'policyStoreId': self.policy_store_id,
			'principal': principal_entity,
			'action': action_entity,
			'resource': resource_entity
		}

		if context:
			request['context'] = {'contextMap': context}

		response = self.client.is_authorized(**request)
		return response['decision'] == 'ALLOW'
	except ClientError as e:
		error_code = e.response['Error']['Code']

		if error_code == 'ResourceNotFoundException':
			print(f"Policy store not found: {self.policy_store_id}")
		elif error_code == 'ValidationException':
			print(f"Invalid request: {e.response['Error']['Message']}")
		elif error_code == 'ThrottlingException':
			print("Request throttled - consider implementing exponential backoff")
		else:
			print(f"AWS error: {error_code}")

		# Fail closed - deny access on error
		return False

	except BotoCoreError as e:
		print(f"SDK error: {e}")
		return False

	except Exception as e:
		print(f"Unexpected error: {e}")
		return False

It’s important to note that the AWS SDK provides built-in retry logic for transient failures. The following is an example of how you can enable this feature:

# Configure retry behavior
config = Config(
	retries={
		'max_attempts': 3,
		'mode': 'adaptive'# Automatically adjusts retry behavior
	},
	connect_timeout=5,
	read_timeout=10
)

self.client = boto3.client(
	'verifiedpermissions',
	region_name=region,
	config=config
)

Data transformation

Your current authorization data needs to be transformed into Cedar’s entity format. This transformation happens in the _to_cedar_entity method shown in the error handling changes example, but let’s break down what’s involved.

Extracting entity information
Identify which parts of your current OPA input represent the principal, resource, and action. In most OPA implementations, this mapping is straightforward:

# Current OPA structure
opa_input = {
	"user": {...},# This becomes the principal
	"resource": {...},# This becomes the resource
	"action": "read"# This becomes the action
}

# Map to Cedar structure
principal = opa_input["user"]
resource = opa_input["resource"]
action = opa_input["action"]

Adding type information
Cedar requires explicit type declarations for all entities. You’ll need to determine the appropriate entity type based on your schema:

def _determine_entity_type(self, entity_data: Dict[str, Any]) -> str:
	# Determine the Cedar entity type based on entity data. This logic will be specific to your application.
	# Example: determine type based on entity structure or type field
	if 'role' in entity_data:
		return 'User'
	elif 'document_type' in entity_data:
		return 'Document'
	elif 'name' in entity_data and 'member_count' in entity_data:
		return 'Team'
	else:
		raise ValueError(f"Cannot determine entity type for: {entity_data}")

def _to_cedar_entity(self, entity_data: Dict[str, Any], entity_type: str = None) -> Dict[str, Any]:
	# Convert application data to Cedar entity format.
	if entity_type is None:
		entity_type = self._determine_entity_type(entity_data)

	return {
		'entityType': f'MyApp::{entity_type}',
		'entityId': str(entity_data.get('id', '')),
		'attributes': entity_data
	}

Structuring attributes
Cedar attributes must match your schema definition, so you might need to transform attribute names or values. This is also a chance to iterate and improve on naming. The following example demonstrates a code pattern to convert attribute names and values in code.

def _prepare_attributes(self, entity_data: Dict[str, Any], entity_type: str) -> Dict[str, Any]:
	#Prepare entity attributes according to Cedar schema requirements.
	attributes = {}

	if entity_type == 'User':
		# Map OPA field names to Cedar schema field names
		attributes = {
			'department': entity_data.get('dept', entity_data.get('department')),
			'jobLevel': int(entity_data.get('job_level', entity_data.get('jobLevel', 0))),
			'email': entity_data.get('email', entity_data.get('email_address'))
		}
	elif entity_type == 'Document':
		attributes = {
			'classification': entity_data.get('classification','internal'),
			'department': entity_data.get('department'),
			'owner': entity_data.get('owner', entity_data.get('owner_id'))
		}

	# Remove None values
	return {k: v for k, v in attributes.items() if v is not None}

Handling context
Separate environmental information from entity data. Context information should not be part of entity attributes.

def prepare_authorization_request(self, user_data, resource_data, action,
						request_metadata=None):

	# Entity data only includes intrinsic properties
	principal = {
		'id': user_data['id'],
		'department': user_data['department'],
		'jobLevel': user_data['job_level']
	}

	resource = {
		'id': resource_data['id'],
		'classification': resource_data['classification'],
		'owner': resource_data['owner']
	}

	# Context includes environmental and request-specific data
	context = {}
	if request_metadata:
		context = {
			'currentHour': request_metadata.get('hour'),
			'ipAddress': request_metadata.get('ip_address'),
			'userAgent': request_metadata.get('user_agent'),
			'requestTime': request_metadata.get('timestamp')
		}
	return self.is_authorized(principal, action, resource, context)

Testing your migration

The most critical aspect of migration testing is verifying that you have correctly migrated your authorization logic from Rego to Cedar. This requires systematic testing with comprehensive test cases.

Test case development

  1. Inventory current policies: Document your current Rego policies, including their decision logic, input data requirements, and expected outcomes for key test scenarios
  2. Create test scenarios: Develop test cases covering all policy branches and edge cases
  3. Capture current behavior: Run your test cases against OPA to establish baseline results
  4. Test Cedar policies: Run the same test cases against your Cedar policies
  5. Analyze differences: Investigate mismatches and adjust policies accordingly

When testing your policies, start with basic, straightforward policies before tackling complex ones. Test both positive cases (should be allowed) and negative cases (should be denied) and include edge cases and boundary conditions. Additionally, test with real production data (anonymized if necessary) to verify that your policies will work effectively when implemented in production.

It’s also important to compare the performance characteristics of your OPA setup with Verified Permissions across several key metrics. These metrics should include average response time for authorization requests, throughput (requests per second), and error rates under normal and stress conditions. During testing, test from the actual deployment environment used by your application and account for network latency to AWS services.

Finally, you should test the complete integration between your application and Verified Permissions across several critical areas. Your integration testing should cover authentication and AWS credential handling, request/response data transformation, error handling and fallback scenarios, connection pooling and resource management, and logging and monitoring integration to help ensure that the components work together seamlessly.

Deployment strategy

A successful migration from OPA to Verified Permissions requires careful planning and a risk-managed deployment approach that minimizes disruption to your production systems.

Phased migration approach

Rather than switching entirely to Verified Permissions in a single step, implement a phased migration to reduce risk.

  1. Parallel deployment: Deploy Verified Permissions alongside your existing OPA infrastructure and route a small percentage of authorization requests to the new system. Log and compare results between both systems, focusing on non-critical operations initially to minimize risk during the transition process.
  2. Gradual traffic shift: Gradually increase the percentage of requests routed to Verified Permissions while monitoring system performance, error rates, and authorization accuracy. Implement circuit breaker patterns to fall back to OPA if needed and expand to more critical operations as your confidence grows in the reliability and performance of the new system.
  3. Full migration: Route all traffic to Verified Permissions but keep OPA infrastructure running temporarily. Monitor system behavior under full production load and decommission OPA infrastructure after stability is confirmed and you are confident in the performance of the new system.

Feature flag implementation

Use feature flags to control the migration process through various flag types. These include percentage-based rollout to route a specific percentage of requests to the new system, user-based rollout to route specific users or user groups to the new system, operation-based rollout to route specific types of operations to the new system, and environment-based rollout to use different systems in different environments. Feature flags provide several benefits, including instant rollback capability if issues arise, granular control over migration scope, A/B testing of authorization decisions, and safe experimentation with new policies.

Troubleshooting common migration issues

When migrating from Rego to Cedar, you might encounter several common issues. In this section, you’ll find a troubleshooting guide.

Complex Rego logic translation

Some Rego policies use complex logic that doesn’t directly translate to Cedar. For example:

# Complex Rego policy with loops and comprehensions
allow {
	some i # The i variable is used to iterate over the items in the input.user.permissions array
		input.user.permissions[i].resource == input.resource.id
		input.user.permissions[i].actions[_] == input.action # The wildcard _ is used to iterate over the items in the actions array
}

In these scenarios, you should restructure your data model to work better with Cedar’s entity-based approach. For example, Cedar provides the in operator for improved performance and readability, as shown in the following example:

permit (
	principal,
	action,
	resource
) when {
	principal has permission &&
	resource in principal.permission.resources &&
	action in principal.permission.actions
};

Schema validation errors

Cedar requires strict schema compliance. Common errors include:

  • Undefined entity types
  • Missing required attributes
  • Type mismatches

You can use the schema validation tools provided by Verified Permissions to triage these issues.

Best practices and recommendations

Adhering to the following recommendations and best practices will help you build a maintainable, secure, and performant authorization system with Verified Permissions.

Policy design best practices

Well-designed policies are the foundation of a reliable authorization system and directly impact maintainability and security:

  • Schema-first design: Start with a comprehensive schema design before writing policies. A well-designed schema makes policy authoring more maintainable.
  • Basic, explicit policies: Favor multiple basic policies over complex monolithic ones. Cedar’s explicit permit/forbid model works best with clear, straightforward policy statements.
  • Meaningful naming: Use descriptive names for entity types, attributes, and policy descriptions. This improves understandability and maintainability of polices.
  • Documentation: Document your authorization model, including entity relationships, policy intentions, and business rules.

Migration strategy recommendations

Successfully migrating your authorization system requires balancing speed with safety through deliberate, incremental steps:

  • Incremental approach Don’t attempt to migrate everything at once. Start with basic, low-risk policies and gradually move to more complex scenarios.
  • Start in audit mode: Calculate and log the policy decisions for both systems. This will help you to compare results without impacting runtime authorization.
  • Comprehensive testing: Invest heavily in testing during migration. The cost of thorough testing is much less than the cost of authorization failures in production.
  • Parallel operations: Run both systems in parallel during migration to validate policy behavior and build confidence in the new system.
  • Team training: Ensure your team understands Cedar’s policy model and syntax. The conceptual differences from Rego require a learning investment.

Operational excellence

Maintaining a production authorization system requires ongoing attention to operational concerns beyond the initial migration:

  • Version control: Treat policies as code with proper version control, code review, and deployment processes.
  • Monitoring and alerting: Implement comprehensive monitoring from day one. Authorization issues can have significant business impact.
  • Regular audits: Periodically review and audit policies to verify that they still meet business requirements and security standards.
  • Performance optimization: Continuously monitor and optimize performance, particularly around caching strategies and policy efficiency.

Conclusion

Migrating from Open Policy Agent to Amazon Verified Permissions represents a significant step toward reducing operational overhead, improving runtime authorization performance and enhancing governance while maintaining robust authorization capabilities. The migration journey from OPA to Verified Permissions isn’t only about changing technologies, it’s an opportunity to improve your authorization architecture, enhance security practices, and build a more scalable foundation for your application’s access control needs.

Thank you for reading this post. If you have comments or questions about migrating from OPA to Verified Permissions, leave them in the comments section below.

Additional resources

The following links provide resources for further reading on the topics covered in this blog post:


If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
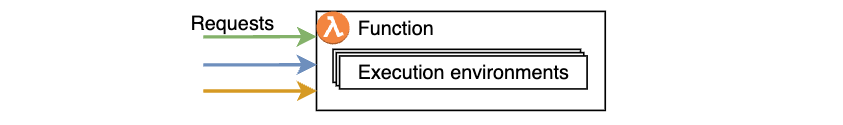
Samuel Folkes

Samuel Folkes
Samuel is a Senior Security Solutions Architect at Amazon Web Services with more than 18 years of experience in software architecture, networking, and cybersecurity. Prior to AWS, he worked as a software engineer and led engineering teams across multiple industries. Samuel specializes in identity and access management and is passionate about using emerging technologies to drive business value.

Orchestrating big data processing with AWS Step Functions Distributed Map

Post Syndicated from Biswanath Mukherjee original https://aws.amazon.com/blogs/compute/orchestrating-big-data-processing-with-aws-step-functions-distributed-map/

Developers seek to process and enrich semi-structured big data datasets with durably orchestrated network-based workflows. For example, during quarterly earnings season, finance organizations run thousands of market simulations simultaneously to provide timely insights for scenario planning or risk management—these workloads require coordination between raw datasets and on-premise servers to provide the latest market information.

AWS Step Functions is a visual workflow service capable of orchestrating over 14,000 API actions from over 220 AWS services to build distributed applications. Now, Step Functions Distributed Map streamlines big data dataset transformation by processing Amazon Athena data manifest and Parquet files directly. Using its Distributed Map feature, you can process large scale datasets by running concurrent iterations across data entries in parallel. In Distributed mode, the Map state processes the items in the dataset in iterations called child workflow executions. You can specify the number of child workflow executions that can run in parallel. Each child workflow execution has its own, separate execution history from that of the parent workflow. By default, Step Functions runs 10,000 parallel child workflow executions in parallel.

Distributed Map can process AWS Athena data manifest and Parquet files directly, eliminating the need for custom pre-processing. You also now have visibility into your Distributed Map usage with new Amazon CloudWatch metrics: Approximate Open Map Runs Count, Open Map Run Limit, and Approximate Map Runs Backlog Size.

In this post, you’ll learn how to use AWS Step Functions Distributed Map to process Athena data manifest and Parquet files through a step-by-step demonstration.

This post is part of a series of post about AWS Step Functions Distributed Map:

Use case: IoT sensor data processing

You’ll build a sample application that demonstrates processing IoT sensor data in Parquet format using Step Functions Distributed Map. These Parquet data files and a manifest file containing the list of the data files are exported from Athena. The data temperature, humidity, and lbattery level from different devices. The following table shows sample of sensor data:

Example IoT sensor data

Example IoT sensor data

Your objective is to use the Athena data manifest file, get the list of Parquet files, and iterate over the data in the files to detect anomalies and also stream the processed data through Amazon Kinesis Data Firehose to an Amazon S3 bucket for further analytics using Athena queries. Following is the criteria to detect anomaly:

  • Low battery conditions: less than 20%
  • Humidity anomalies: more than 95% or less than 5%
  • Temperature spikes: more than 35°C or less than -10°C

The following diagram represents the AWS Step Functions state machine:

Parquet files processing workflow

Parquet files processing workflow

  1. The Distributed Map runs an Athena query which generates Parquet data files and an Athena manifest file (csv). The manifest file contains the list of Parquet data files.
  2. Distributed Map processes these Parquet data files in parallel using child workflow executions. You can control the number of child workflow executions that can run in parallel using MaxConcurrency parameter. See Step Functions service quotas to learn more about concurrency limits.
  3. Each child workflow execution invokes an AWS Lambda function to process the respective Parquet file. The Lambda function processes individual sensor readings and detects anomalies according to the preceeding logic and returns a processed sensor data summary response.
  4. The child workflow sends the summary response record to Amazon Kinesis firehose stream which stores the results in a specified Amazon S3 results bucket.

The following Athena Start QueryExecution state runs an UNLOAD query to generate data files in Parquet format and a manifest file in CSV. The output will be stored in the S3 bucket specified in the UNLOAD query and the manifest file will be stored in the S3 bucket configured for the Athena workgroup.

{
  "QueryLanguage": "JSONata",
  "States": {
	   "Athena StartQueryExecution": {
	    "Type": "Task",
	        "Resource": "arn:aws:states:::athena:startQueryExecution.sync",
	        "Arguments": {
		"QueryString": "UNLOAD (WRITE_YOUR_SELECT_QUERY_HERE) TO 'S3_URI_FOR_STORING_DATA_OBJECT' WITH (format = 'JSON')",
		"WorkGroup": "primary"
	},
	"Output": {
	"ManifestObjectKey": "{% $join([$states.result.QueryExecution.ResultConfiguration.OutputLocation, '-manifest.csv']) %}"
},
“Next”: “Next State”
…
}

The following ItemReader is configured to use a manifest type of “ATHENA_DATA” with “PARQUET” data input.

{
  "QueryLanguage": "JSONata",
  "States": {
    ...
    "Map": {
        ...
        "ItemReader": {
        	"Resource": "arn:aws:states:::s3:getObject",
   	"ReaderConfig": {
      		"ManifestType": "ATHENA_DATA",
      		"InputType": "PARQUET"
   	},
   	"Arguments": {
      		"Bucket":"Bucket": "{% $split($substringAfter($states.input.ManifestObjectKey, 's3://'), '/')[0] %}",,
      		"Key": "{% $substringAfter($substringAfter($states.input.ManifestObjectKey, 's3://'), '/') %}"
   	}
	    },
        ...
    }
}

Additional supported InputType options are CSV and JSONL. All objects referenced in a single manifest file must have the same InputType format. You specify the Amazon S3 bucket location of Athena manifest CSV file under Arguments.

The context object contains information in a JSON structure about your state machine and execution. Your workflows can reference the context object in a JSONata expression with $states.context.

Within a Map state, the Context object includes the following data:

"Map": {
   "Item": {
      "Index" : Number,
      "Key"   : "String", // Only valid for JSON objects
      "Value" : "String",
      "Source": "String"
   }
}

For each Map state iteration, Index contains the index number for the array item that is being currently processed, Key is available only when iterating over JSON objects, Value contains the array item being processed, and Source contains one of the following:

  • For state input, the value will be : STATE_DATA
  • For Amazon S3 LIST_OBJECTS_V2 with Transformation=NONE, the value will show the S3 URI for the bucket. For example: S3://amzn-s3-demo-bucket.
  • For all the other input types, the value will be the Amazon S3 URI. For example: S3://amzn-s3-demo-bucket/object-key.

Using this newly introduced Source field in the context object, you can connect the child executions with the source object.

Prerequisites

Set up the state machine and sample data

Run the following steps to deploy the Step Functions state machine.

  1. Clone the GitHub repository in a new folder and navigate to the project root folder.
    git clone https://github.com/aws-samples/sample-stepfunctions-athena-manifest-parquet-file-processor.git
    cd sample-stepfunctions-athena-manifest-parquet-file-processor

  2. Run the following command to install required Python dependencies for the Lambda function.
    python3 -m venv .venv
    source .venv/bin/activate
    python3 -m pip install -r requirements.txt

  3. Build the application.
    sam build

  4. Deploy the application
    sam deploy --guided

  5. Enter the following details:
    • Stack name: The CloudFormation stack name (for example, sfn-parquet-file-processor)
    • AWS Region: A supported AWS Region (for example, us-east-1)
    • Keep rest of the components to default values.

    Note the outputs from the AWS SAM deploy. You will use them in the subsequent steps.

  6. Run the following command to generate sample data in csv format and upload it to an S3 bucket. Replace <IoTDataBucketName> with the value from sam deploy ouptut.
    python3 scripts/generate_sample_data.py <IoTDataBucketName>

Create the Athena database and tables

Before you can run queries, you must set up an Athena database and table for your data.

  1. From Amazon Athena console, navigate to workgoups, select the workgroup named “primary”. Select Edit from Actions. In the query result configuration section, select the options as follows:
    1. Management of query results – select customer managed
    2. Location of query results – enter s3://<IoTDataBucketName>. Replace <IoTDataBucketName> with the value from sam deploy output.
    3. Choose Save to save the changes to the workgroup
  2. Select Query editor tab and run the following commands to create database and tables
    CREATE DATABASE `iotsensordata`;

  3. Create an Athena table in database iotsensordata that references the S3 bucket containing the raw sensor data. In this case it will be <IoTDataBucketName>. Replace <IoTDataBucketName> with the value from sam deploy output.
    CREATE EXTERNAL TABLE IF NOT EXISTS `iotsensordata`.`iotsensordata` 
    (`deviceid` string, 
    `timestamp` string,
    `temperature` double,
    `humidity` double,
    `batterylevel` double,
    `latitude` double,
    `longitude` double
    )
    ROW FORMAT SERDE 'org.apache.hadoop.hive.serde2.lazy.LazySimpleSerDe'
    WITH SERDEPROPERTIES ('field.delim' = ',')
    STORED AS INPUTFORMAT 'org.apache.hadoop.mapred.TextInputFormat' OUTPUTFORMAT 'org.apache.hadoop.hive.ql.io.HiveIgnoreKeyTextOutputFormat'
    LOCATION 's3://<IoTDataBucketName>/daily-data/'
    TBLPROPERTIES (
     'classification' = 'csv',
     'skip.header.line.count' = '1'
    );

  4. Create an Athena table in database iotsensordata that references the S3 bucket having the analytics results streamed from Kinesis Data Firehose. Replace <IoTAnalyticsResultsBucket> with value from sam deploy output. And replace <year> with the current year (e.g 2025).
    CREATE EXTERNAL TABLE IF NOT EXISTS iotsensordata.iotsensordataanalytics (deviceid string, analysisDate string, readingTimestamp string, readingsCount int, metrics struct< temperature: double, humidity: double, batterylevel: double, latitude: double, longitude: double >, anomalies array <string>, anomalyCount int, healthStatus string, timestamp string )
    ROW FORMAT SERDE 'org.openx.data.jsonserde.JsonSerDe'
    WITH SERDEPROPERTIES ( 'ignore.malformed.json' = 'FALSE', 'dots.in.keys' = 'FALSE', 'case.insensitive' = 'TRUE'
    )
    STORED AS INPUTFORMAT 'org.apache.hadoop.mapred.TextInputFormat' OUTPUTFORMAT 'org.apache.hadoop.hive.ql.io.HiveIgnoreKeyTextOutputFormat'
    LOCATION 's3://<IoTAnalyticsResultsBucket>/<year>/'
    TBLPROPERTIES ('classification' = 'json', 'typeOfData'='file');

Start your state machine

Now that you have data ready and Athena set up for queries, start your state machine to retrieve and process the data.

  1. Run the following command to start execution of the Step Functions. Replace the <StateMachineArn> and <IoTDataBucketName> with the value from sam deploy output..
    aws stepfunctions start-execution \
      --state-machine-arn <StateMachineArn> \
      --input '{ "IoTDataBucketName": "<IoTDataBucketName>"}'

    The Step Functions state machine has the Athena StartQueryExecution state which has an UNLOAD query that generates the sensor data files in a parquet format and a manifest file in CSV format. The manifest will have 5 rows referencing the 5 parquet files. The state machine will process these 5 parquet files in one map run.

  2. Run the following command to get the details of the execution. Replace the executionArn from the previous command.
    aws stepfunctions describe-execution --execution-arn <executionArn>

  3. After you see the status SUCCEEDED, run the following command from Athena query editor to check the processed output from Kinesis Data Firehose that was streamed to S3 bucket referenced by the Athena table created in step 4 of the preceding section.
    SELECT * FROM iotsensordata.iotsensordataanalytics WHERE anomalycount = 1;

If any of the sensor data exceeds the thresholds, the healthstatus attribute will be set to “anomalies_detected”. The workflow produced a summary table of metadata which you can now query for reporting.

Output from Athena Query Editor

Review workflow performance

Using the following observability metrics, you can review key performance behavior of your data processing workflow.
The AWS/States namespace includes the following new metrics for all Step Functions Map Runs.

  • OpenMapRunLimit: This is the maximum number of open Map Runs allowed in the AWS account. The default value is 1,000 runs and is a hard limit. For more information, see Quotas related to accounts.
  • ApproximateOpenMapRunCount: This metric tracks the approximate number of Map Runs currently in progress within an account. Configuring an alarm on this metric using the Maximum statistic with a threshold of 900 or higher can help you take proactive action before reaching the OpenMapRunLimit of 1,000. This metric enables operational teams to implement preventive measures, such as staggering new executions or optimizing workflow concurrency, to maintain system stability and prevent backlog accumulation.
  • ApproximateMapRunBacklogSize: This metric shows up when the ApproximateOpenMapRunCount has reached 1,000 and there are backlogged Map Runs waiting to be executed. Backlogged Map Runs wait at the MapRunStarted event until the total number of open Map Runs is less than the quota.

The following graph shows an example of these new metrics. Use the maximum statistic to visualize these metrics. ApproximateMapRunBacklogSize metrics appear after accounts start getting throttled on the OpenMapRunLimit limit. The OpenMapRun (orange line) is the account hard limit of 1,000 shown as a static line. The ApproximateOpenMapRunCount (violet line) is the current number of active OpenMap runs. The ApproximateMapRunBacklogSize (green line) indicates the map runs waiting in backlog to be processed. When the ApproximateOpenMapRunCount is lower than 1000 (OpenMapRun limit) there are no map runs in backlog. However, when the count reaches the OpenMapRun limit, the backlog of map runs starts to build up. After the active runs complete, the backlog will start to drain out and new runs will begin execution.

Graphed metrics from Amazon CloudWatch

Graphed metrics from Amazon CloudWatch

Clean up

To avoid costs, remove all resources created for this post once you’re done. From the Athena query editor, run the following commands:

DROP TABLE `iotsensordata`.`iotsensordata`;
DROP TABLE `iotsensordata`.`iotsensordataanalytics`;
DROP DATABASE `iotsensordata`;

Run the following commands from the AWS CLI after replacing the <placeholder> variable to delete the resources you deployed for this post’s solution:

aws s3 rm s3://<IoTDataBucketName> --recursive
aws s3 rm s3://<IoTAnalyticsResultsBucketName> --recursive
sam delete

Conclusion

With this update, Distributed Map now supports additional data inputs, so you can orchestrate large-scale analytics and ETL workflows. You can now process Amazon Athena data manifest and Parquet files directly, eliminating the need for custom pre-processing. You also now have visibility into your Distributed Map usage with the following metrics: Approximate Open Map Runs Count, Open Map Run Limit, and Approximate Map Runs Backlog Size.

New input sources for Distributed Map are available in all commercial AWS Regions where AWS Step Functions is available. For a complete list of AWS Regions where Step Functions is available, see the AWS Region Table. The improved observability of your Distributed Map usage with new metrics is available in all AWS Regions. To get started, you can use the Distributed Map mode today in the AWS Step Functions console. To learn more, visit the Step Functions developer guide.

For more serverless learning resources, visit Serverless Land.

Optimizing nested JSON array processing using AWS Step Functions Distributed Map

Post Syndicated from Biswanath Mukherjee original https://aws.amazon.com/blogs/compute/optimizing-nested-json-array-processing-using-aws-step-functions-distributed-map/

When you’re working with large datasets, you’ve likely encountered the challenge of processing complex JSON structures in your automated workflows. You need to preprocess arrays within nested JSON objects before you can run parallel processing on them. Extracting data used to require custom code and extra processing steps, delaying you from building your core application logic.

With AWS Step Functions Distributed Map, you can process large datasets with concurrent iterations of workflow steps across data entries. Using the enhanced ItemsPointer feature of Distributed Maps, you can extract array data directly from JSON objects stored in Amazon S3. Alternatively, for JSON object as state input, you can use Items (JSONata) or ItemsPath (JSONPath). With this enhancement you can point directly to arrays nested within JSON structures, eliminating the need for custom preprocessing of your data. With ItemsPointer, Items, and ItemsPath you can select the nested array data and simplify your workflows.

In this post, we explore how to optimize processing array data embedded within complex JSON structures using AWS Step Functions Distributed Map. You’ll learn how to use ItemsPointer to reduce the complexity of your state machine definitions, create more flexible workflow designs, and streamline your data processing pipelines—all without writing additional transformation code or AWS Lambda functions.

This post is part of a series of post about AWS Step Functions Distributed Map:

Use case: e-commerce product data enrichment

In this e-commerce use case example, you’ll build a sample application that demonstrates processing of product inventory data for an e-commerce application using AWS Step Functions Distributed Map. The application receives a JSON file from an upstream application containing an array of product information. The Step Functions workflow reads the JSON file containing product data from an S3 bucket and iterates over the array to enrich each product data in the array.

The following diagram presents the AWS Step Functions state machine.

JSON array processing workflow

JSON array processing workflow

The JSON array is processed using the following workflow:

  1. The state machine reads the product-updates.json file from an input S3 bucket. The file contains a JSON array of products.
  2. The Distributed Map state in the state machine, selects the JSON array node using ItemsPointer and iterates over the JSON array.
  3. For each of the items within the array, the state machine invokes a Lambda function for data enrichment. The Lambda function adds product stock and price information to the product data.
  4. The state machine saves the updated product data in an Amazon DynamoDB table.
  5. Finally, the state machine uploads the execution metadata into an output S3 bucket. See limits related to state machine executions and task executions.

MaxConcurrency can be configured to specify the number of child workflow executions in a Distributed Map that can run in parallel. If not specified, then Step Functions doesn’t limit concurrency and runs 10,000 parallel child workflow executions.

You can read a JSON file from a S3 bucket using ItemReader and its sub-fields. If the JSON file, from the S3 bucket, contains a nested object structure, you can select the specific node with your data set with an ItemsPointer. For example, the following input JSON file:

{
  "version": "2024.1",
  "timestamp": "2025-09-26T10:49:36.646197",
  "productUpdates": {
    "items": [
      {
        "productId": "PROD-001",
        "name": "Wireless Headphones",
        "price": 79.99,
        "stock": 150,
        "category": "Electronics"
      },
      {
        "productId": "PROD-002",
        "name": "Smart Watch",
        "category": "Electronics"
      },
      …
    ]
  }
}

The following JSONata-based workflow configuration extracts a nested list of products from productUpdates/items:

"ItemReader": {
   "Resource": "arn:aws:states:::s3:getObject",
   "ReaderConfig": {
      "InputType": "JSON",
      "ItemsPointer": "/productUpdates/items"
   },
   "Arguments": {
      "Bucket": "amzn-s3-demo-bucket",
      "Key": "updates/product-updates.json"
   }
}

For JSONPath-based workflow note that Arguments is replaced with Parameters:

"ItemReader": {
   "Resource": "arn:aws:states:::s3:getObject",
   "ReaderConfig": {
      "InputType": "JSON",
      "ItemsPointer": "/productUpdates/items"
   },
   "Arguments": {
      "Bucket": "amzn-s3-demo-bucket",
      "Key": "updates/product-updates.json"
   }
}

The ItemReader field is not needed when your dataset is JSON data from a previous step. ItemsPointer is only applicable when the input JSON objects read from an S3 bucket. If you are using JSON as state input to a Distributed Map, then you can use the ItemsPath (for JSONPath) or Items (for JSONata) field to specify a location in the input that points to JSON array or object used for iterations.

Prerequisite

To use Step Functions Distributed Map, verify you have:

Set up and run the workflow

Run the following steps to deploy the Step Functions state machine.

  1. Clone the GitHub repository in a new folder and navigate to the project folder.
    git clone https://github.com/aws-samples/sample-stepfunctions-json-array-processor.git
    cd sample-stepfunctions-json-array-processor

  2. Run the following commands to deploy the application.
    sam deploy --guided

    Enter the following details:

    • Stack name: Stack name for CloudFormation (for example, stepfunctions-json-array-processor)
    • AWS Region: A supported AWS Region (for example, us-east-1)
    • Accept all other default values.

    The outputs from the sam deploy will be used in the subsequent steps.

  3. Run the following command to generate product-updates.json file containing a nested JSON array of sample products and upload the product-updates.json file to the input S3 bucket. Replace InputBucketName with the value from sam deploy output.
    python3 scripts/generate_sample_data.py <InputBucketName>

  4. Run the following command to start execution of the Step Functions workflow. Replace the StateMachineArn with the value from sam deploy output.
    aws stepfunctions start-execution \
      --state-machine-arn <StateMachineArn> \
      --input '{}'

    The state machine reads the input product-updates.json file and invokes a Lambda function to update the database for every product in the array after adding price and stock information. The execution metadata is also uploaded into the results bucket.

Monitor and verify results

Run the following steps to monitor and verify the test results.

  1. Run the following command to get the details of the execution. Replace executionArn with your state machine ARN.
    aws stepfunctions describe-execution --execution-arn <executionArn>

    Wait until the status shows SUCCEEDED.

  2. Run the following commands to validate the processed output from ProductCatalogTableName DynamoDB table. Replace the value ProductCatalogTableName with the value from sam deploy output.
    aws dynamodb scan --table-name <ProductCatalogTableName>

  3. Check that the DynamoDB table contains the enriched product data including price and stock attributes. Example output:
    {
        "Items": [
            {
                "ProductId": {
                    "S": "PROD-005"
                },
                "lastUpdated": {
                    "S": "2025-10-07T20:33:34.507Z"
                },
                "stock": {
                    "N": "129"
                },
                "price": {
                    "N": "139.25"
                }
            },
            {
                "ProductId": {
                    "S": "PROD-003"
                },
                "lastUpdated": {
                    "S": "2025-10-07T20:33:34.576Z"
                },
                "stock": {
                    "N": "471"
                },
                "price": {
                    "N": "40.92"
                }
            },
    	      …
        ],
        "Count": 5,
        "ScannedCount": 5,
        "ConsumedCapacity": null
    }

Clean up

To avoid costs, remove all resources you’ve created while following along with this post.

Run the following command after replacing the <placeholder> variable to delete the resources you deployed for this post’s solution:

aws s3 rm s3://<InputBucketName> --recursive
aws s3 rm s3://<ResultBucketName> --recursive
sam delete

Conclusion

In this post, you learned how to use Step Functions Distributed Map for extracting array data natively from JSON objects stored in a S3 bucket. By removing custom data extraction code, you can simplify the processing of your large-scale parallel workloads. With ItemsPointer you can extract array data within JSON files stored in a S3 bucket , and with Items(JSONata) or ItemsPath (JSONPath), you can extract arrays from complex JSON state input, adding flexibility to your workflow designs.

New input sources for Distributed Map are available in all commercial AWS Regions where AWS Step Functions is available. For a complete list of AWS Regions where Step Functions is available, see the AWS Region Table. To get started, you can use the Distributed Map mode today in the AWS Step Functions console. To learn more, visit the Step Functions developer guide.

For more serverless learning resources, visit Serverless Land.

Enhanced search with match highlights and explanations in Amazon SageMaker

Post Syndicated from Ramesh H Singh original https://aws.amazon.com/blogs/big-data/enhanced-search-with-match-highlights-and-explanations-in-amazon-sagemaker/

Amazon SageMaker now enhances search results in Amazon SageMaker Unified Studio with additional context that improves transparency and interpretability. Users can see which metadata fields matched their query and understand why each result appears, increasing clarity and trust in data discovery. The capability introduces inline highlighting for matched terms and an explanation panel that details where and how each match occurred across metadata fields such as name, description, glossary, and schema. Enhanced search results reduces time spent evaluating irrelevant assets by presenting match evidence directly in search results. Users can quickly validate relevance without analyzing individual assets.

In this post, we demonstrate how to use enhanced search in Amazon SageMaker.

Search results with context

Text matches include keyword match, begins with, synonyms, and semantically related text. Enhanced search displays search result text matches in these locations:

  • Search result: Text matches in each search result’s name, description, and glossary terms are highlighted.
  • About this result panel: A new About this result panel is displayed to the right of the highlighted search result. The panel displays the text matches for the result item’s searchable content including name, description, glossary terms, metadata, business names, and table schema. The list of unique text match values is displayed at the top of the panel for quick reference.

Data catalogs contain thousands of datasets, models, and projects. Without transparency, users can’t tell why certain results appear or trust the ordering. Users need evidence for search relevance and understandability.

Enhanced search with match explanations improves catalog search in four key ways:
1) transparency is increased because users can see why a result appeared and gain trust,
2) efficiency improves since highlights and explanations reduce time spent opening irrelevant assets,
3) governance is supported by showing where and how terms matched, aiding audit and compliance processes, and
4) consistency is reinforced by revealing glossary and semantic relationships, which reduces misunderstanding and improves collaboration across teams.

How enhanced search works

When a user enters a query, the system searches across multiple fields like name, description, glossary terms, metadata, business names and table schema. With enhanced search transparency, each search result includes the list of text matches that were the basis for including the result, including the field that contained the text match, and a portion of the field’s text value before and after the text match, to provide context. The UI uses this information to display the returned text with the text match highlighted.

For example, a steward searches for “revenue forecasting,” and an asset is returned with the name “Sales Forecasting Dataset Q2” and a description that contains “projected sales figures.” The word sales is highlighted in the name and description, in both the search result and the text matches panel, because sales is a synonym for revenue. The About this result panel also shows that forecast was matched in the schema field name sales_forecast_q2.

Solution overview

In this section we demonstrate how to use the enhanced search features. In this example, we will be demonstrating the use in a marketing campaign where we need user preference data. While we have multiple datasets on users, we will demonstrate how enhanced search simplifies the discovery experience.

Prerequisites

To test this solution you should have an Amazon SageMaker Unified Studio domain set up with a domain owner or domain unit owner privileges. You should also have an existing project to publish assets and catalog assets. For instructions to create these assets, see the Getting started guide.

In this example we created a project named Data_publish and loaded data from the Amazon Redshift sample database. To ingest the sample data to SageMaker Catalog and generate business metadata, see Create an Amazon SageMaker Unified Studio data source for Amazon Redshift in the project catalog.

Asset discovery with explainable search

To find assets with explainable search:

  1. Log in to SageMaker Unified Studio.
  2. Enter the search text user-data. While we get the search results in this view, we want to get further details on each of these datasets. Press enter to go to full search.
  3. In full search, search results are returned when there are text matches based on keyword search, starts with, synonym, and semantic search. Text matches are highlighted within the searchable content that is shown for each result: in the name, description, and glossary terms.
  4. To further enhance the discovery experience and find the right asset, you can look at the About this result panel on the right and see the other text matches, for example, in the summary, table name, data source database name, or column business name, to better understand why the result was included.
  5. After examining the search results and text match explanations, we identified the asset named Media Audience Preferences and Engagement as the right asset for the campaign and selected it for analysis.

Conclusion

Enhanced search transparency in Amazon SageMaker Unified Studio transforms data discovery by providing clear visibility into why assets appear in search results. The inline highlighting and detailed match explanations help users quickly identify relevant datasets while building trust in the data catalog. By showing exactly which metadata fields matched their queries, users spend less time evaluating irrelevant assets and more time analyzing the right data for their projects.

Enhanced search is now available in AWS Regions where Amazon SageMaker is supported.

To learn more about Amazon SageMaker, see the Amazon SageMaker documentation.


About the authors

Ramesh H Singh

Ramesh H Singh

Ramesh is a Senior Product Manager Technical (External Services) at AWS in Seattle, Washington, currently with the Amazon DataZone team. He is passionate about building high-performance ML/AI and analytics products that enable enterprise customers to achieve their critical goals using cutting-edge technology.

Pradeep Misra

Pradeep Misra

Pradeep is a Principal Analytics and Applied AI Solutions Architect at AWS. He is passionate about solving customer challenges using data, analytics, and AI/ML. Outside of work, Pradeep likes exploring new places, trying new cuisines, and playing board games with his family. He also likes doing science experiments, building LEGOs and watching anime with his daughters.

Ron Kyker

Ron Kyker

Ron is a Principal Engineer with Amazon DataZone at AWS, where he helps drive innovation, solve complex problems, and set the bar for engineering excellence for his team. Outside of work, he enjoys board gaming with friends and family, movies, and wine tasting.

Rajat Mathur

Rajat Mathur

Rajat is a Software Development Manager at AWS, leading the Amazon DataZone and SageMaker Unified Studio engineering teams. His team designs, builds, and operates services which make it faster and straightforward for customers to catalog, discover, share, and govern data. With deep expertise in building distributed data systems at scale, Rajat plays a key role in advancing the data analytics and AI/ML capabilities of AWS.

Kyle Wong

Kyle Wong

Kyle is a Software Engineer at AWS based in San Francisco, where he works on the Amazon DataZone and SageMaker Unified Studio team. His work has been primarily at the intersection of data, analytics, and artificial intelligence, and he is passionate about developing AI-powered solutions that address real-world customer challenges.

Use trusted identity propagation for Apache Spark interactive sessions in Amazon SageMaker Unified Studio

Post Syndicated from Aarthi Srinivasan original https://aws.amazon.com/blogs/big-data/use-trusted-identity-propagation-for-apache-spark-interactive-sessions-in-amazon-sagemaker-unified-studio/

Amazon SageMaker Unified Studio introduces support for running interactive Apache Spark sessions with your corporate identities through trusted identity propagation. These Spark interactive sessions are available using Amazon EMR, Amazon EMR Serverless, and AWS Glue. Enterprises with their workforce corporate identity provider (IdP) integrated with AWS IAM Identity Center can now use their IAM Identity Center user and group identity seamlessly with SageMaker Unified Studio to access AWS Glue Data Catalog databases and tables.

Administrators of AWS services can use trusted identity propagation in IAM Identity Center to grant permissions based on user attributes, such as user ID or group associations. With trusted identity propagation, identity context is added to an IAM role to identify the user requesting access to AWS resources and is further propagated to other AWS services when requests are made. Until now, Spark sessions in SageMaker Unified Studio used the project IAM role for managing data access permissions for all members of the project. This provided fine-grained access control at the project IAM role level and not at the user level. Now, with the trusted identity propagation enabled in the SageMaker Unified Studio domain, the data access can be fine-grained at the user or group level.

The trusted identity propagation support for Spark interactive sessions makes the SageMaker Unified Studio a holistic offering for enterprise data users. Enabling trusted identity propagation in SageMaker Unified Studio saves time by avoiding the repeated permission grants to new project IAM roles and enhances security auditing with the IAM Identity Center user or group ID in the AWS CloudTrail logs.

The following are some of the use cases for trusted identity propagation in Spark sessions for SageMaker Unified Studio:

  • Single sign-on experience with AWS analytics – For customers using enterprise data mesh built using AWS Lake Formation, single sign-on experience with trusted identity propagation is available for Spark applications through EMR Studio attached with Amazon EMR on EC2 and SQL experience through Amazon Athena query editor inside EMR Studio. With the addition of EMR Serverless, Amazon EMR on EC2, and AWS Glue for Spark sessions with trusted identity propagation enabled in SageMaker Unified Studio, the single sign-on experience is expanded to provide easier options for the data scientists and developers.
  • Fine-grained access control based on user identity or group membership– Use a single project within the SageMaker Unified Studio domain across multiple data scientists, with the fine-grained permissions of AWS Lake Formation. When a data scientist accesses the AWS Glue Data Catalog table, the session is now enabled by their IAM Identity Center user or group permissions. Further, each can use their preferred tool, such as EMR Serverless, AWS Glue, or Amazon EMR on Amazon Elastic Compute Cloud (Amazon EC2), for the Spark sessions inside SageMaker Unified Studio.
  • Isolated user sessions – The Spark interactive sessions in SageMaker Unified Studio are securely isolated for each IAM Identity Center user. With secure sessions, data teams can focus more on business data exploration and faster development cycles, rather than building guardrails.
  • Auditing and reporting – Customers in regulated industries need strict compliance reports showing fine-grained details of their data access. CloudTrail logs provide the additionalContext field with the details of IAM Identity Center user ID or group ID and the analytics engine that accessed the Data Catalog tables from SageMaker Unified Studio.
  • Expand and scale with unified governance model – Customers who are already using Amazon Redshift, Amazon QuickSight and AWS Lake Formation permissions integrated with IAM Identity Center can now expand their ML and data analytics platform to include Spark sessions with EMR Serverless and AWS Glue options in SageMaker Unified Studio. They don’t have to maintain IAM role-based policy permissions. Trusted identity propagation for Spark sessions in SageMaker Unified Studio scales the existing permissions mechanism to a wider community of data scientists and developers.

In this post, we provide step-by-step instructions to set up Amazon EMR on EC2, EMR Serverless, and AWS Glue within SageMaker Unified Studio, enabled with trusted identity propagation. We use the setup to illustrate how different IAM Identity Center users can run their Spark sessions, using each compute setup, within the same project in SageMaker Unified Studio. We show how each user will see only tables or part of tables that they’re granted access to in Lake Formation.

Solution overview

A financial services company processes data from millions of retail banking transactions per day, pooled into their centralized data lake and accessed by traditional corporate identities. Their machine learning (ML) platform team would like to enable thousands of their data scientists, working across different teams, with the right dataset and tools in a secure, scalable and auditable fashion. The platform team chooses to use SageMaker Unified Studio, integrate their IdP with IAM Identity Center, and manage access for their data scientists on the data lake tables using fine-grained Lake Formation permissions.

In our sample implementation, we show how to enable three different data scientists—Arnav, Maria, and Wei—belonging to two different teams, to access the same datasets, but with different levels of access. We use Lake Formation tags to grant column restricted access and have the three data scientists run their Spark sessions within the same SageMaker Unified Studio project. When the individual users sign in to the SageMaker Unified Studio project, their IDC user or group identity context is added to the SageMaker Unified Studio project execution role, and their fine-grained permissions from Lake Formation on the catalog tables are effective. We show how their data exploration is isolated and unique.

The following diagram shows an instance of how an enterprise workforce IdP, integrated with IAM Identity Center, would make the users and groups available for use by AWS services. Here, Lake Formation and SageMaker Unified Studio domain are integrated with IAM Identity Center and trusted identity propagation is enabled. In this setup, (a) data permissions are granted to the IDC user or group identities directly instead of IAM roles (b) the user identity context is available end-to-end (c) data access control is centralized in Lake Formation no matter which analytics service the user uses.

Prerequisites

Working with IAM Identity Center and the AWS services that integrate with IAM Identity Center requires several steps. In this post we use one AWS account with IAM Identity Center enabled and a SageMaker Unified Studio domain created. We recommend that you use a test account to follow along the blog.

You need the following prerequisites:

  • An AWS account setup with an IAM administrator role that has permissions to work with IAM Identity Center, Lake Formation, Amazon Simple Storage Service (Amazon S3), CloudTrail, SageMaker Unified Studio, Amazon EMR on EC2, EMR Serverless, and AWS Glue.
  • Enable IAM Identity Center in the account. For details, refer to Enable IAM Identity Center.
    1. Three IAM Identity Center users (Arnav, Maria, and Wei) and two groups (DataScientists and MarketAnalytics). For instructions on creating IAM Identity Center users, refer to Add users to your Identity Center directory. For instructions on creating groups, refer to Add groups to your Identity Center directory.
    2. Add Arnav and Maria to the DataScientists group and add Wei to the MarketAnalytics group. For instructions on adding users to groups, refer to Add users to groups.

    The following screenshot shows users Maria and Arnav in the DataScientists group.

    following screenshot shows user Wei in the MarketAnalytics group.

  • Configure Lake Formation. For detailed instructions, refer to Data lake administrator permissions and Set up AWS Lake Formation in the Lake Formation documentation.
    1. Integrate Lake Formation with the IAM Identity Center instance. For instructions, refer to Integrating IAM Identity Center.
  • A database and a table created in AWS Glue Data Catalog, with the table data in an S3 bucket.
    1. For the sample dataset and table used in this post, refer to Appendix A.
  • Lake Formation tag-based permissions for the three IAM Identity Center users on the Data Catalog table.
    1. For creating and assigning LF-Tags to Data Catalog tables, refer to Creating LF-Tags, and Assigning LF-Tags to Data Catalog resources.
    2. For granting permissions using LF-Tags, refer to Granting data lake permissions using the LF-TBAC method.
    3. We have shown the sample LF-Tags and permissions for the IAM Identity Center users in Appendix B.
  • A SageMaker Unified Studio domain domain-tip-smus-blog. For instructions to create a SageMaker Unified Studio domain, refer to the quick setup guide in the SageMaker Unified Studio documentation.
    1. The domain should be enabled with trusted identity propagation, following the instructions in Trusted identity propagation.
    2. The domain’s project profile should be enabled with Amazon EMR on EC2. You can choose either General purpose or Memory-Optimized profile. You will have to provide a value for certificateLocation, as shown in the following screenshot. For detailed instructions, refer to Specify PEM certificate for EmrOnEc2 blueprint. For this post, you can use OpenSSL to generate a self-signed X.509 certificate with a 2048-bit RSA private key. Detailed instructions for creating one are at the bottom of Create keys and certificates for data encryption with Amazon EMR.
    3. The two IAM Identity Center groups (DataScientists and MarketAnalytics) should be added to the domain as users. For instructions, refer to Managing users in Amazon SageMaker Unified Studio.

Create a project in SageMaker Unified Studio

Now that DataScientists and MarketAnalytics groups are granted access to the domain, IAM Identity Center users belonging to those two groups can sign in to the SageMaker Unified Studio portal for the next steps. Follow these steps:

  1. Sign in to the SageMaker Unified Studio portal as single sign-on user Arnav.
  2. Create a project blogproject_tip_enabled under the domain, as shown in the following screenshot. For details, follow the instructions in Create a project.
  3. Select All capabilities for Project profile, as shown in the following screenshot. Leave the other parameters to default values.

Arnav would like to collaborate with other team members. After creating the project, he grants access on the project to additional IAM Identity Center groups. He adds the two IAM Identity Center groups, DataScientists and MarketAnalytics, as Members of type Contributor to the project, as shown in the following screenshot.

So far, you’ve set up IAM Identity Center, created users and groups, created a SageMaker Unified Studio domain and project, and added the IAM Identity Center groups as users to the domain and the project. In the rest of the sections, we set up the three types of computes for Spark interactive session and enter a query on the Lake Formation managed tables as individual IAM Identity Center users Arnav, Maria, and Wei.

Set up EMR Serverless

In this section, we set up an EMR Serverless compute and run a Spark interactive session as Arnav.

  1. Sign in to the SageMaker Unified Studio domain as the single sign-on user Arnav. Refer to the domain’s detail page to get the URL.
  2. After signing in as Arnav, select the project blogproject_tip_enabled. From the left navigation pane, choose Compute. On the Data processing tab, choose Add compute.
  3. Under Add compute, choose Create new compute resources, as shown in the following screenshot.
  4. Choose EMR Serverless.
  5. Under Release label, choose minimum version 7.8.0 and choose Fine-grained.
  6. After the EMR Serverless compute is in Created status, on the Actions dropdown list, choose Open JupyterLab IDE. This will open a Jupyter Notebook session.
  7. When the Jupyter notebook opens, you will see a banner to update the SageMaker Distribution image to version 2.9. Follow the instructions in Editing a space and update the space to use version 2.9. Save the space and restart after update.
  8. Open the space after it finishes updating. This will open the Jupyter notebook.

    Now, your environment is ready, and you can run Spark queries and test your access to the table bankdata_icebergtbl.
  9. On the Launcher window, under Notebook, choose Python 3(ipykernel).
  10. On the top part of the notebook cell, choose PySpark from the kernel dropdown list and emr-s.blog_tipspark_emrserverless from the Compute dropdown list.
  11. Run the following query:
    spark.sql(“select * from bankdata_db.bankdata_icebergtbl limit 10”).show()

Because Arnav is part of the DataScientists group, he should see all columns of the table, as shown in the following screenshot.

This verifies LF-Tags based access for Arnav on the bankdata_db.bankdata_icebergtbl using a Spark session in EMR Serverless compute.

Set up AWS Glue 5.0

In this section, we set up AWS Glue compute and run a Spark interactive session as Maria.

  1. Sign in to the SageMaker Unified Studio domain as the single sign-on user Maria.
  2. Choose the project blogproject_tip_enabled. From the left navigation pane, choose Compute. On Data processing tab, you should see two computes created by default in Active status (project.spark.compatibility and project.spark.fineGrained) with Type Glue ETL. For additional details on these compute types, refer to AWS Glue ETL in Amazon SageMaker Unified Studio.
  3. Select the project.spark.fineGrained and launch the Jupyter notebook with the PySpark kernel.
  4. For the notebook cell, choose pySpark for kernel and project.spark.fineGrained for compute. Enter the following query:
    sspark.sql(“select * from bankdata_db.bankdata_icebergtbl limit 10”).show()

Because Maria is part of the DataScientists group, she should see all columns of the table, as shown in the following screenshot.

This verifies LF-Tags based access to Maria on the bankdata_db.bankdata_icebergtbl using Spark session in AWS Glue fine-grained access control (FGAC) compute.

To verify what access Wei has using EMR Serverless and AWS Glue, you can sign out and sign in as user Wei. Enter the Spark SELECT queries on the same table. Wei shouldn’t see the three personally identifiable information (PII) columns transaction_id, bank_account_number, and initiator_name, which were tagged as transactions=secured.

The following screenshot shows the same table for Wei using EMR Serverless.

The following screenshot shows the same table for Wei using AWS Glue FGAC mode.

Set up Amazon EMR on EC2

In this section, we set up an Amazon EMR on EC2 compute and run a Spark interactive session as Wei.

  1. Sign in to the SageMaker Unified Studio domain as the single sign-on user Wei.
  2. Create Amazon EMR on EC2 compute using the steps for EMR Serverless in Setup EMR serverless but choose EMR on EC2 cluster instead of EMR Serverless. For the EMR configuration, choose the MemoryOptimized or GeneralPurpose configuration, depending on which one you chose to upload your PEM certificates to in the project profiles blueprint in the Prerequisites section. Choose an Amazon EMR release label greater than or equal to 7.8.0.
  3. After the cluster is provisioned, locate the instance profile role name in the compute details page, as shown in the following screenshot.
  4. As an admin user who can edit IAM policies in your account, add the following inline policy to the instance profile role. A manual intervention outside SageMaker Unified Studio is required currently to perform this step. This will be addressed in the future.
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Sid": "IdCPermissions",
                "Effect": "Allow",
                "Action": [
                    "sso-oauth:CreateTokenWithIAM",
                    "sso-oauth:IntrospectTokenWithIAM",
                    "sso-oauth:RevokeTokenWithIAM"
                ],
                "Resource": "*"
            },
            {
                "Sid": "AllowAssumeRole",
                "Effect": "Allow",
                "Action": [
                    "sts:AssumeRole"
                ],
                "Resource": [
                    "<instance profile role ARN>"
                ]
            }
        ]
    }

  5. After updating the role’s policy, you can use the Amazon EMR on EC2 connection to initiate an interactive Spark session. Similar to how you launched a notebook as Arnav and Maria, do the same steps to launch the notebook as user Wei.
    1. On the Build tab, choose JupyterNotebook from the project home page. Choose Python3(ipykernel) to launch the notebook. Choose Configure space to update to version 2.9. Refresh the notebook browser.
    2. Inside the notebook, on top of the cell, choose PySpark for kernel and emr.blog_tip_emronec2 that you launched for the compute.
  6. Enter a select query on the table as follows:
    spark.sql(“select * from bankdata_db.bankdata_icebergtbl limit 10”).show()

This verifies that Wei, as part of the MarketAnalytics group, sees all columns of the table with LF-Tags transactions=accessible but doesn’t have access to the three columns that were overwritten with LF-Tags transactions=secured (transaction_id, bank_account_number, and initiator_name).

You can trace the user access of the table in the CloudTrail logs for EventName=GetDataAccess. In the relevant CloudTrail log shown below, we notice that the UserID for Wei is provided under additionalEventData field, whereas requestParameters has the tableARN.

The user ID for Wei is available in the IAM Identity Center console under General information.

Thus, we were able to sign in as an individual IAM Identity Center user to the SageMaker Unified Studio domain and query the Data Catalog tables using Amazon EMR and AWS Glue compute. These IAM Identity Center users were able to query the tables that they were granted access to, instead of the SageMaker Unified Studio project’s IAM role.

Cleanup

To avoid incurring costs, it’s important to delete the resources launched for this walkthrough. Clean up the resources as follows:

  1. SageMaker Unified Studio by default shuts down idle resources such as JupyterLab after 1 hour. If you’ve created a SageMaker Unified Studio domain for this post, remember to delete the domain.
  2. If you’ve created IAM Identity Center users and groups, delete the users and delete the groups. Further, if you’ve created an IAM Identity Center instance only for this post, delete your IAM Identity Center instance.
  3. Delete the database bankdata_db from Lake Formation. This will also delete the tables and all associated permissions. Delete the LF-Tag transactions and its values.
  4. Delete the table’s corresponding data from your S3 bucket two subfolders bankdata-csv and bankdata-iceberg.

Conclusion

In this post, we walked through how to enable a SageMaker Unified Studio domain with IAM Identity Center trusted identity propagation and query Lake Formation managed tables in Data Catalog using Apache Spark interactive sessions with EMR Serverless, AWS Glue, and Amazon EMR on EC2. We also verified in CloudTrail logs the IAM Identity Center user ID accessing the table.

Amazon SageMaker Unified Studio with trusted identity propagation provides the following benefits.

Business benefits

  • Enhanced data security
  • Improved workforce data access and insights

Technical capabilities

  • Enables data access based on workforce identity
  • Provides unified governance through Lake Formation for Data Catalog tables when accessed through SMUS
  • Ensures isolated and secure sessions for each IAM Identity Center user
  • Supports multiple analytics options:
    • Spark sessions via EMR Serverless, EMR on EC2, and AWS Glue
    • SQL analytics through Athena and Redshift Spectrum

Organizational advantages

  • Direct use of corporate identities for enterprise data access
  • Simplified access to data platforms and meshes built on Data Catalog and Lake Formation
  • Enables various user roles to work with their preferred AWS analytics services
  • Reduces data exploration time for Spark-familiar data scientists

To learn more, refer to the following resources:

We encourage you to check out the new trusted identity propagation enabled SageMaker Unified Studio for Spark sessions. Reach out to us through your AWS account teams or using the comments section.

Acknowledgment: A special thanks to everyone who contributed to the development and launch of this feature: Palani Nagarajan, Karthik Seshadri, Vikrant Kumar, Yijie Yan, Radhika Ravirala and Jerica Nicholls.

APPENDIX A – Table creation in Data Catalog

  1. We’ve created a synthetic bank transactions dataset with 100 rows in CSV format. Download the dataset dummy_bank_transaction_data.csv
  2. In your S3 bucket, create two subfolders: bankdata-csv and bankdata-iceberg and upload the dataset to bankdata-csv.
  3. Open the Athena console, navigate to query editor, and enter the following statements in sequence:
    -- Create database for the blog
    CREATE DATABASE bankdata_db;
    
    -- Create external table from the CSV file. Provide your S3 bucket name for the table location
    
    CREATE EXTERNAL TABLE bankdata_db.bankdata_csvtbl(
     `transaction_id` string, 
      `transaction_date` date, 
      `transaction_type` string,
      `bank_account_number` string,
      `initiator_name` string,
      `transaction_country` string, 
      `transaction_amount` double, 
      `merchant_name` string)
    ROW FORMAT DELIMITED FIELDS TERMINATED BY ',' 
    STORED AS INPUTFORMAT 'org.apache.hadoop.mapred.TextInputFormat' 
    OUTPUTFORMAT 'org.apache.hadoop.hive.ql.io.HiveIgnoreKeyTextOutputFormat'
    LOCATION 's3://<your-bucket-name>/bankdata-csv/'
    TBLPROPERTIES (
      'areColumnsQuoted'='false', 
      'classification'='csv', 
      'skip.header.line.count'='1',
      'columnsOrdered'='true', 
      'compressionType'='none', 
      'delimiter'=',', 
      'typeOfData'='file');
     
    -- Create Iceberg table for the blog use. Provide your S3 bucket name for the table location
    
    CREATE TABLE bankdata_db.bankdata_icebergtbl WITH (
      table_type='ICEBERG',
      format='parquet',
      write_compression = 'SNAPPY',
      is_external = false,
      partitioning=ARRAY['transaction_type'],
      location='s3://<your-bucket-name>/bankdata-iceberg/'
    ) AS SELECT * FROM bankdata_db.bankdata_csvtbl;

  4. Enter a preview and verify the table data:
    SELECT * FROM bankdata_db.bankdata_icebergtbl limit 10;

APPENDIX B – Creating LF-Tags, attaching tags to the table from Appendix A, and granting permissions to IAM Identity Center users.

We create a Lake Formation tag with Keyname = transactions and Values = secured, accessible. We associate the tag to the table and overwrite a few columns as summarized in the table.

Resource

LF-Tag association

Database

bankdata_db

transactions = accessible

Table

bankdata_icebergtbl

transactions = accessible
Columns transaction_id transactions = secured
bank_account_number transactions = secured
initiator_name transactions = secured

We then grant Lake Formation permissions to the two IAM Identity Center groups using these LF-Tags as follows:

IAM Identity Center group

LF-Tags

Permission

DataScientists

transactions = accessible AND transactions = secured

Database DESCRIBE, Table SELECT

MarketAnalytics

transactions = accessible

Database DESCRIBE, Table SELECT
  1. Sign in to the Lake Formation console and navigate to LF-Tags and permissions. Create an LF-Tag with Keyname = transactions and Values = secured, accessible.
  2. Select the database bankdata_db and associate the LF-Tag transactions=accessible.
  3. Select bankdata_icebergtbl and verify that the LF-Tag transactions=accessible is inherited by the table.
  4. Edit the schema of the table and change the LF-Tag value on the columns transaction_id, bank_account_number, and initiator_name to transactions=secured. After changing, choose Save as new version.


  5. Navigate to the Data permissions page on the Lake Formation console. Choose Grant to grant permissions.
  6. Select the IAM Identity Center group DataScientists for Principals. Select LF-Tags transactions and both the values accessible, secured. Choose Database DESCRIBE and Tables SELECT permissions. Choose Grant.
  7. On the Data permissions page on the Lake Formation console, choose Grant again.
  8. Select the IAM Identity Center group MarketAnalytics for Principals. Select LF-Tags transactions and only one of the values, accessible. Select Database DESCRIBE and Tables SELECT permissions. Choose Grant.
  9. Also grant DESCRIBE permission on the default database to both the IDC groups.
  10. Verify the granted permissions in the Data permissions page, by filtering with expression Principal type = IAM Identity Center group.

Thus, we’ve granted all column access on the table bankdata_icebergtbl to the DataScientists group while securing three PII columns from the MarketAnalytics group.


About the Authors

Aarthi Srinivasan

Aarthi Srinivasan

Aarthi is a Senior Big Data Architect at Amazon Web Services (AWS). She works with AWS customers and partners to architect data lake solutions, enhance product features, and establish best practices for data governance.

Palani Nagarajan

Palani Nagarajan

Palani is a Senior Software Development Engineer with Amazon SageMaker Unified Studio. In his free time, he enjoys playing board games, traveling to new cities, and hiking scenic trails.

Processing Amazon S3 objects at scale with AWS Step Functions Distributed Map S3 prefix

Post Syndicated from Biswanath Mukherjee original https://aws.amazon.com/blogs/compute/processing-amazon-s3-objects-at-scale-with-aws-step-functions-distributed-map-s3-prefix/

If you’re building large scale enterprise applications, you’ve likely faced the complexities of processing large volumes of data files. Whether you’re analyzing your application logs, processing customer data files, or transforming machine learning datasets, you know the complexity involved in orchestrating workflows. You’ve probably written nested workflows and additional custom code to process objects from Amazon Simple Storage Service (Amazon S3) buckets.

With AWS Step Functions Distributed Map, you can process large scale datasets by running concurrent iterations of workflow steps across data entries in parallel, achieving massive scale with simplified management.

With the new prefix-based iteration feature and LOAD_AND_FLATTEN transformation parameter for Distributed Map, your workflows can now iterate over S3 objects under a specified prefix using S3ListObjectsV2 to process their contents in a single Map state, avoiding nested workflows and reducing operational complexity.

In this post, you’ll learn how to process Amazon S3 objects at scale with the new AWS Step Functions Distributed Map S3 prefix and transformation capabilities.

Use case: Application log processing and summarization

You’ll build a sample Step Functions state machine that demonstrates processing of all the log files from the given S3 prefix using a Distributed Map. You’ll analyze all the log files to build a summary INFO, WARNING and ERROR messages in the log file on hourly basis. The following diagram presents the AWS Step Functions state machine:

Log files processing workflow

Log files processing workflow

  1. The state machine iterates over all the log files from the specified S3 prefix using S3 ListObjectsV2 and process them using AWS Step Functions Distributed Map.
  2. For each log file entry, the state machine puts hourly ErrorCount metric into Amazon CloudWatch.
  3. The state machine then stores hourly metrics count in a Amazon DynamoDB table.
  4. The state machine then invokes an AWS Lambda function to perform metrics aggregation.

The following is an example of the parameters in an ItemReader configured to iterate over the content of S3 objects using S3 ListObjectsV2.

{
  "QueryLanguage": "JSONata",
  "States": {
    ...
    "Map": {
        ...
        "ItemReader": {
            "Resource": "arn:aws:states:::s3:listObjectsV2",
            "ReaderConfig": {
                // InputType is required if Transformation is LOAD_AND_FLATTEN. Use one of the given values
                "InputType": "CSV | JSON | JSONL | PARQUET",
                // Transformation is OPTIONAL and defaults to NONE if not present
                "Transformation": "NONE | LOAD_AND_FLATTEN" 
            },
            "Arguments": {
                "Bucket": "amzn-s3-demo-bucket1",
                "Prefix": "{% $states.input.PrefixKey %}"
            }
        },
        ...
    }
}

With the LOAD_AND_FLATTEN option, your state machine will do the following:

  1. Read the actual content of each object listed by the Amazon S3 ListObjectsV2 call.
  2. Parse the content based on InputType (CSV, JSON, JSONL, Parquet).
  3. Create items from the file contents (rows/records) rather than metadata.

We recommend including a trailing slash on your prefix. For example, if you select data with a prefix of folder1, your state machine will process both folder1/myData.csv and folder10/myData.csv. Using folder1/ will strictly process only one folder. All of the objects listed by prefix need to be in the same data format. For example, if you are selecting InputType as JSONL, your S3 prefix should contain only JSONL files and not a mix of other types.

The context object is an internal JSON structure that is available during an execution. The context object contains information about your state machine and execution. Your workflows can reference the context object in a JSONata expression with $states.context.

Within a Map state, the context object includes the following data:

"Map": {
   "Item": {
      "Index" : Number,
      "Key"   : "String", // Only valid for JSON objects
      "Value" : "String",
      "Source": "String"
   }
}

For each Map iteration, the Index contains the index number for the array item that is being currently processed.

A Key is only available when iterating over JSON objects. Value contains the array item being processed. For example, for the following input JSON object, Names will be assigned to Key and {"Bob", "Cat"} will be assigned to Value.

{
	"Names": {"Bob", "Cat"}
} 

Source contains one of the following:

  • For state input: STATE_DATA
  • For Amazon S3 LIST_OBJECTS_V2 with Transformation=NONE, the value will show the S3 URI for the bucket. For example: S3://amzn-s3-demo-bucket1
  • For all the other input types, the value will be the Amazon S3 URI. For example: S3://amzn-s3-demo-bucket1/object-key

Using LOAD_AND_FLATTEN and the Source field, you can connect child executions to their sources.

Prerequisites

Set up and run the workflow

Run the following steps to deploy and test the Step Functions state machine.

  1. Clone the GitHub repository in a new folder and navigate to the project folder.
    git clone https://github.com/aws-samples/sample-stepfunctions-s3-prefix-processor.git
    cd sample-stepfunctions-s3-prefix-processor

  2. Run the following commands to deploy the application.
    sam deploy --guided

  3. Enter the following details:
    • Stack name: Stack name for CloudFormation (for example, stepfunctions-s3-prefix-processor)
    • AWS Region: A supported AWS Region (for example, us-east-1)
    • Accept all other default values.

    The outputs from the AWS SAM deploy will be used in the subsequent steps.

  4. Run the following command to generate sample log files.
    python3 scripts/generate_logs.py

  5. Run the following to upload the log files to the S3 bucket with the /logs/daily prefix. Replace amzn-s3-demo-bucket1 with the value from the sam deploy output.
    aws s3 sync logs/ s3://amzn-s3-demo-bucket1/logs/ --exclude '*' --include '*.log'

  6. Run the following command to execute the Step Functions workflow. Replace the StateMachineArn with the value from the sam deploy output.
    aws stepfunctions start-execution \
      --state-machine-arn <StateMachineArn> \
      --input '{}'

    The Step Function state machine iterates over all the log files with the S3 prefix /logs/daily and processes them in parallel. The workflow updates the metrics in CloudWatch, stores hourly metrics count in DynamoDB, then invokes an AWS Lambda function to aggregate the metrics.

Monitor and verify results

Run the following steps to monitor and verify the test results.

  1. Run the following command to get the details of the execution. Replace executionArn with your state machine ARN.
    aws stepfunctions describe-execution --execution-arn <executionArn>

  2. When the status shows SUCCEEDED, run the following commands to check the processed output from the LogAnalyticsSummaryTableName DynamoDB table. Replace the value LogAnalyticsSummaryTableName with the value from the sam deploy output.
    aws dynamodb scan --table-name <LogAnalyticsSummaryTableName>

  3. Check that hourly ERROR, WARN, and INFO logs statistics are saved in the DynamoDB table. The following is a sample output:
    {
        "Items": [
            {
                "ProcessingTime": {
                    "S": "2025-10-07T23:45:10.790Z"
                },
                "WarningCount": {
                    "N": "2"
                },
                "HourOfDay": {
                    "S": "13"
                },
                "TotalRecords": {
                    "N": "5"
                },
                "ErrorCount": {
                    "N": "3"
                },
                "InfoCount": {
                    "N": "0"
                },
                "HourKey": {
                    "S": "2025-10-08 13"
                }
            },
            {
                "ProcessingTime": {
                    "S": "2025-10-07T23:45:07.456Z"
                },
                "WarningCount": {
                    "N": "3"
                },
                "HourOfDay": {
                    "S": "09"
                },
                "TotalRecords": {
                    "N": "6"
                },
                "ErrorCount": {
                    "N": "2"
                },
                "InfoCount": {
                    "N": "1"
                },
                "HourKey": {
                    "S": "2025-10-08 09"
                }
            },
            …
    ],
        "Count": 24,
        "ScannedCount": 24,
        "ConsumedCapacity": null
    }

  4. Run the following command to check the output of the Step Functions state machine execution output.
    aws stepfunctions describe-execution --execution-arn <executionArn> --query 'output' --output text

    The following is a sample output:

    {
      "Summary": {
        "date": "2025-10-08",
        "totalErrors": 50,
        "totalWarnings": 41,
        "totalRecords": 133,
        "hourlyBreakdown": {
          "00": {
            "errors": 1,
            "warnings": 3,
            "records": 5
          },
          "01": {
            "errors": 1,
            "warnings": 1,
            "records": 5
          },
          "02": {
            "errors": 2,
            "warnings": 3,
            "records": 5
          },
          "03": {
            "errors": 3,
            "warnings": 2,
            "records": 7
          },
    …
    …
        "generatedAt": "2025-10-08T05:19:05.603889"
      }
    }

    The output of the Step Functions state machine shows the daily summary insights of the log files created by the Lambda function.

Clean up

To avoid costs, remove all resources created for this post once you’re done. Run the following command after replacing amzn-s3-demo-bucket1 with your own bucket name to delete the resources you deployed for this post’s solution:

aws s3 rm s3://amzn-s3-demo-bucket1 --recursive
sam delete
rm -rf logs/

Conclusion

In this post, you learned how AWS Step Functions Distributed Map can use prefix-based iteration with LOAD_AND_FLATTEN transformation to read and process multiple data objects from Amazon S3 buckets directly. You no longer need one step to process object metadata and another to load the data objects. Loading and flatting in one step is particularly valuable for data processing pipelines, batch operations, and event-driven architectures where objects are continually added to S3 locations. By eliminating the need to maintain object manifests, you can build more resilient, dynamic data processing workflows with less code and fewer moving parts.

New input sources for Distributed Map are available in all commercial AWS Regions where AWS Step Functions is available. To get started, you can use the Distributed Map mode today in the AWS Step Functions console. To learn more, visit the Step Functions developer guide.

For more serverless learning resources, visit Serverless Land.

Accelerate data governance with custom subscription workflows in Amazon SageMaker

Post Syndicated from Nira Jaiswal original https://aws.amazon.com/blogs/big-data/accelerate-data-governance-with-custom-subscription-workflows-in-amazon-sagemaker/

Amazon SageMaker provides a single data and AI development environment to discover and build with your data. This unified platform integrates functionality from existing AWS Analytics and Artificial Intelligence and Machine Learning (AI/ML) services, including Amazon EMR, AWS Glue, Amazon Athena, Amazon Redshift, and Amazon Bedrock.

Organizations need to efficiently manage data assets while maintaining governance controls in their data marketplaces. Although manual approval workflows remain important for sensitive datasets and production systems, there’s an increasing need for automated approval processes with less sensitive datasets. In this post, we show you how to automate subscription request approvals within SageMaker, accelerating data access for data consumers.

Prerequisites

For this walkthrough, you must have the following prerequisites:

  • An AWS account – If you don’t have an account, you can create one. The account should have permission to do the following:
    • Create and manage SageMaker domains
    • Create and manage IAM roles
    • Create and invoke Lambda functions
  • SageMaker domain – For instructions to create a domain, refer to Create an Amazon SageMaker Unified Studio domain – quick setup.
  • A demo project – Create a demo project in your SageMaker domain. For instructions, see Create a project. For this example, we choose All capabilities in the project profile section.
  • SageMaker domain ID, project ID, and project role ARN – These will be used in later steps to provide permissions for existing datasets and resources, and automatic subscription approval code. To retrieve this information, go to the Project details tab on the project details page on the SageMaker console.
  • AWS CLI installed – You must have the AWS Command Line Interface (AWS CLI) version 2.11 or later.
  • Python installed – You must have Python version 3.8 or later.
  • IAM permissions – Sign in as the user with administrative access
  • Lambda permissions – Configure the appropriate IAM permissions for the Lambda execution role. The following code is a sample role used for testing this solution. Before implementing this IAM policy in your environment, provide the values for your specific AWS Region and account ID. Adjust them based on the principle of least privilege. To learn more about creating Lambda execution roles, refer to Defining Lambda function permissions with an execution role.
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Effect": "Allow",
                "Action": [
                    "datazone:ListSubscriptionRequests",
                    "datazone:AcceptSubscriptionRequest",
                    "datazone:GetSubscriptionRequestDetails",
                    "datazone:GetDomain",
                    "datazone:ListProjects"
                ],
                "Resource": "<<Domain-ARN>>"
            },
            {
                "Effect": "Allow",
                "Action": "sts:AssumeRole",
                "Resource": "<<Domain-ARN>>",
                "Condition": {
                    "StringEquals": {
                        "aws:PrincipalArn": "<<Lambda ARN>>"
                    }
                }
            },
            {
                "Effect": "Allow",
                "Action": "sns:Publish",
                "Resource": "<<SNS-ARN>>"
            },
            {
                "Effect": "Allow",
                "Action": [
                    "logs:CreateLogGroup",
                    "logs:CreateLogStream",
                    "logs:PutLogEvents"
                ],
                "Resource": [
                    "arn:aws:logs:${AWS::Region}:${AWS::AccountId}:log-group:/aws/lambda/*",
                    "arn:aws:logs:${AWS::Region}:${AWS::AccountId}:log-group:/aws/lambda/*:*"
                ]
            }
        ]
    }

Solution overview

Understanding the subscription and approval workflow in Amazon SageMaker is important before diving deep into custom workflow solution. After an asset is published to the SageMaker catalog, data consumers can discover assets. When a data consumer discovers assets in SageMaker catalog, they request access to the asset, by submitting a subscription request with business justification and intended use case. The request enters a pending state and notifies the data producer or asset owner for review. The data producer evaluates the request based on governance policies, consumer credentials, and business context. The data producer can accept, reject, or request additional information from the data consumer. Upon acceptance, SageMaker triggers the AcceptSubscriptionRequest event and begins automated access provisioning. After a subscription is accepted, a subscription fulfilment process gets kicked off to facilitate access to the asset, for the data producer. SageMaker integrates deeply with AWS Lake Formation to manage fine-grained permissions. When a subscription is approved, SageMaker automatically calls Lake Formation APIs to grant specific database, table, and column-level permissions to the subscriber’s IAM role. Lake Formation acts as the central permission engine, translating subscription approvals into actual data access rights without manual intervention. The system provisions and updates resource-based policies on data sources. Once the provisioning completes, the data consumer can immediately access subscribed data through query engines like Athena, Redshift, or EMR, with Lake Formation enforcing permissions at query time.

By default, subscription requests to a published asset require manual approval by a data owner. However, Amazon SageMaker supports automatic approval of subscription requests at asset level: when publishing a data asset, you can choose to not require subscription approval. In this case, all incoming subscription requests to that asset are automatically approved. Let’s first outline the step-by-step process for disabling automatic approval at the asset level.

Configure automatic approval at asset level:

To configure automatic approval, data producers can follow the steps below.

  1. Log in to SageMaker Unified Studio portal as data producer. Navigate to Assets and select the target asset
  2. Choose Assets → Pick the asset, which you would like to configure for automatic approval.
  3. On the asset details page, locate Edit Subscription settings in the right pane.
  4. Choose Edit next to Subscription Required
    1. Select Not Required in the dialogue box
    2. Confirm your selection

Customize SageMaker’s subscription workflow:

While manual approval workflow remains essential for production environments and sensitive data handling, organizations seek to streamline and automate approvals for lower-risk environments and non-sensitive datasets. To achieve this project-level automation, we can enhance SageMaker’s native approval workflow through a custom event-driven solution. This solution leverages AWS’s serverless architecture, combining using AWS Lambda, Amazon EventBridge rules, and Amazon Simple Notification Service (Amazon SNS) to create an automated approval workflow. This customization allows organizations to maintain governance while reducing administrative overhead and accelerating the development cycle in non-critical environments. The event-driven approach ensures real-time processing of approval requests, maintains audit trails, and can be configured to apply different approval rules based on project characteristics and data sensitivity levels.

The custom workflow consists of the following steps:

  1. The data consumer submits a subscription request for a published data asset.
  2. SageMaker detects the request and generates a subscription event, which is automatically sent to EventBridge.
  3. EventBridge triggers the designated Lambda function.
  4. The Lambda function sends an AcceptSubscriptionRequest API call to SageMaker.
  5. The function also sends a notification through Amazon SNS.
  6. AWS Lake Formation processes the approved subscription and updates the relevant access control lists (ACLs) and permission sets.
  7. Lake Formation grants access permissions to the data consumer’s project AWS Identity and Access Management (IAM) role.
  8. The data consumer now has authorized access to the requested data asset and can begin working with the subscribed data.

The following diagram illustrates the high-level architecture of the solution.

Key benefits

This solution uses AWS Lambda and Amazon EventBridge to automate SageMaker subscription requests approvals, delivering the following benefits for organizations and end-users:

  • Scalability – Automatically handles high volumes of subscription requests
  • Cost-efficiency – Pay-as-you-go approach with no idle resource costs
  • Minimal maintenance – Serverless components require no infrastructure management
  • Flexible triggering – Supports event-driven, scheduled, and manual invocation modes
  • Audit compliance – Comprehensive logging and traceability through AWS CloudTrail

Step-by-step procedure

This section outlines the detailed process for implementing a custom subscription request approval workflow in Amazon SageMaker

Create Lambda function

Complete the following steps to create your Lambda function:

  1. On the Lambda console, choose Functions in the navigation pane.
  2. Choose Create function.
  3. Select Author from scratch.
  4. For Function name, enter a name for the function.
  5. For Runtime, choose your runtime (for this post, we use Python version 3.9 or later).
  6. Choose Create function.
  7. On the Lambda function page, choose the Configuration tab and then choose Permissions.
  8. Note the execution role to use when configuring the SageMaker project.

Create SNS topic

For this solution, we create SNS topic. Complete the following steps to create the SNS topic for automatic approvals:

  1. On the Amazon SNS console, choose Topics in the navigation pane.
  2. Choose Create topic.
  3. For Type, select Standard.
  4. For Name, enter a name for the topic.
  5. Choose Create topic.
  6. On the SNS topic details page, note the SNS topic Amazon Resource Name (ARN) to use later in the Lambda function.
  7. On Subscription tab, choose Create Subscription.
  8. For Protocol, choose Email.
  9. For Endpoint, enter email address of Data consumers.

Create EventBridge rule

Complete the following steps to create an EventBridge rule to capture subscription request events:

  1. On the EventBridge console, choose Rules in the navigation pane.
  2. Choose Create rule.
  3. For Name, enter a name for the rule.
  4. For Rule type, select Rule with event pattern.
    This option enables the automatic subscription approval workflow to be triggered when a subscription request is initiated. Alternatively, you can select Schedule to schedule the rule to trigger on a regular basis. Refer to Creating a rule that runs on a schedule in Amazon EventBridge to learn more.
  5. Choose Next.
  6. For Event source, select AWS events or EventBridge partner events.
  7. For Creation method, select Use pattern form
  8. For Event source, select AWS services
  9. For AWS service, select DataZone.
  10. For Event type, select Subscription Request Created.
  11. Configure your target to route events to both the Lambda function and SNS topic.
  12. Choose Next.
  13. For this post, skip configuring tags and choose Next.
  14. Review the settings and choose Create rule.

Configure automation workflow

Complete the following steps to configure the automation workflow:

  1. On the Lambda console, go to the function you created.
  2. Configure the EventBridge rule to trigger the Lambda function
  3. Configure the destination as SNS topic for event notification.

Configure code in Lambda function

Complete the following steps to configure your Lambda function:

  1. On the Lambda console, go to the function you created.
  2. Add the following code to your function. Provide the domain ID, project ID, and SNS topic ARN that you noted earlier.
    import boto3
    import json
    import logging
    import os
    from botocore.exceptions import ClientError
    
    # Configure logging
    logger = logging.getLogger()
    logger.setLevel(logging.INFO)
    
    def lambda_handler(event, context):
        """Lambda function to auto-approve subscription requests in Amazon SageMaker"""
        try:
            # Initialize clients
            datazone_client = boto3.client('datazone')
            sns_client = boto3.client('sns')
            
            # Get configuration from environment variables or use hardcoded values
            domain_id = os.environ.get('DOMAIN_ID', '<domain_id>')
            project_id = os.environ.get('PROJECT_ID', '<project_id>')
            sns_topic_arn = os.environ.get('SNS_TOPIC_ARN', '<sns_topic_arn>')
            
            # Get pending subscription requests
            pending_requests = get_pending_requests(datazone_client, domain_id, project_id)
            
            if not pending_requests:
                logger.info("No pending subscription requests found")
                return
            
            # Process requests
            for request in pending_requests:
                approve_request(datazone_client, sns_client, domain_id, request, sns_topic_arn)
                
        except Exception as e:
            logger.error(f"Error: {str(e)}")
    
    def get_pending_requests(client, domain_id, project_id):
        """Get all pending subscription requests"""
        requests = []
        next_token = None
        
        try:
            while True:
                params = {
                    'domainIdentifier': domain_id,
                    'status': 'PENDING',
                    'approverProjectId': project_id
                }
                
                if next_token:
                    params['nextToken'] = next_token
                
                response = client.list_subscription_requests(**params)
                
                if 'items' in response:
                    requests.extend(response['items'])
                
                next_token = response.get('nextToken')
                if not next_token:
                    break
                    
            logger.info(f"Found {len(requests)} pending requests")
            return requests
            
        except ClientError as e:
            logger.error(f"Error listing requests: {e}")
            return []
    
    def approve_request(datazone_client, sns_client, domain_id, request, sns_topic_arn):
        """Approve a subscription request and send notification"""
        request_id = request.get('id')
        if not request_id:
            return
            
        try:
            # Approve the request
            datazone_client.accept_subscription_request(
                domainIdentifier=domain_id,
                identifier=request_id,
                decisionComment="Subscription request is auto-approved by Lambda"
            )
            
            # Send notification
            asset_name = request.get('assetName', 'Unknown asset')
            
            message = f"Your subscription request has been auto-approved by Lambda. You can now access this asset."
            
            sns_client.publish(
                TopicArn=sns_topic_arn,
                Subject=f"Subscription Request is auto-approved by Lambda",
                Message=message
            )
            
            logger.info(f"Approved request {request_id} for {asset_name}")
            
        except Exception as e:
            logger.error(f"Error processing request {request_id}: {e}")

  3. Choose Test to test the Lambda function code. To learn more about testing Lambda code, refer to Testing Lambda functions in the console.
  4. Choose Deploy to deploy the code.

Configure Lambda and project execution roles in SageMaker

Complete the following steps:

  1. In SageMaker Unified Studio, go to your publishing project.
  2. Choose Members in the navigation pane.
  3. Choose Add members.
  4. Add the Lambda execution role and project execution roles as Contributor.

Test the solution

Complete the following steps to test the solution:

  1. In SageMaker Unified Studio, navigate to the data catalog and choose Subscribe on the configured asset to initiate a subscription request.
  2. Choose Subscription requests in the navigation pane to view the outgoing requests and choose the Approved tab to verify automatic approval.
  3. Choose View subscription to confirm the approver appears as the Lambda execution role with “Auto-approved by Lambda” as the reason.
  4. On the CloudTrail console, choose Event history to view the event you created and review the automated approval audit trail.

Clean up

To avoid incurring future charges, clean up the resources you created during this walkthrough. The following steps use the AWS Management Console, but you can also use the AWS CLI.

  1. Delete the SageMaker domain. To use the AWS CLI, run the following commands:
    aws sagemaker delete-project --project-name <project-name>
    aws datazone delete-domain –identifier <domain_identifier>

  2. Delete the SNS topics. To use the AWS CLI, run the following command:
    aws sns delete-topic --topic-arn <topic-arn>

  3. Delete the Lambda function. To use the AWS CLI, run the following command:
    aws lambda delete-function --function-name <Lambda function name>

Conclusion

Combining an event-driven architecture with SageMaker creates an automated, cost-effective solution for data governance challenges. This serverless approach automatically handles data access requests while maintaining compliance, so organizations can scale efficiently as their data grows. The solution discussed in this post can help data teams access insights faster with minimal operational costs, making it an excellent choice for businesses that need quick, compliant data access while keeping their systems lean and efficient.

To learn more, visit the Amazon SageMaker Unified Studio page.


About the authors

Nira Jaiswal

Nira Jaiswal

Nira is a Principal Data Solutions Architect at AWS. Nira works with strategic customers to architect and deploy innovative data and analytics solutions. She excels at designing scalable, cloud-based platforms that help organizations maximize the value of their data investments. Nira is passionate about combining analytics, AI/ML, and storytelling to transform complex information into actionable insights that deliver measurable business value.

Ajit Tandale

Ajit Tandale

Ajit is a Senior Solutions Architect at AWS, specializing in data and analytics. He partners with strategic customers to architect secure, scalable data systems using AWS services and open-source technologies. His expertise includes designing data lakes, implementing data pipelines, and optimizing big data processing workflows to help organizations modernize their data architecture. Outside of work, he’s an avid reader and science fiction movie enthusiast.

Implement fine-grained access control for Iceberg tables using Amazon EMR on EKS integrated with AWS Lake Formation

Post Syndicated from Tejal Patel original https://aws.amazon.com/blogs/big-data/implement-fine-grained-access-control-for-iceberg-tables-using-amazon-emr-on-eks-integrated-with-aws-lake-formation/

The rise of distributed data processing frameworks such as Apache Spark has revolutionized the way organizations manage and analyze large-scale data. However, as the volume and complexity of data continue to grow, the need for fine-grained access control (FGAC) has become increasingly important. This is particularly true in scenarios where sensitive or proprietary data must be shared across multiple teams or organizations, such as in the case of open data initiatives. Implementing robust access control mechanisms is crucial to maintain secure and controlled access to data stored in Open Table Format (OTF) within a modern data lake.

One approach to addressing this challenge is by using Amazon EMR on Amazon Elastic Kubernetes Service (Amazon EKS) and incorporating FGAC mechanisms. With Amazon EMR on EKS, you can run open source big data frameworks such as Spark on Amazon EKS. This integration provides the scalability and flexibility of Kubernetes, while also using the data processing capabilities of Amazon EMR.

On February 6th 2025, AWS introduced fine-grained access control based on AWS Lake Formation for EMR on EKS from Amazon EMR 7.7 and higher version. You can now significantly enhance your data governance and security frameworks using this feature.

In this post, we demonstrate how to implement FGAC on Apache Iceberg tables using EMR on EKS with Lake Formation.

Data mesh use case

With FGAC in a data mesh architecture, domain owners can manage access to their data products at a granular level. This decentralized approach allows for greater agility and control, making sure data is accessible only to authorized users and services within or across domains. Policies can be tailored to specific data products, considering factors like data sensitivity, user roles, and intended use. This localized control enhances security and compliance while supporting the self-service nature of the data mesh.

FGAC is especially useful in business domains that deal with sensitive data, such as healthcare, finance, legal, human resources, and others. In this post, we focus on examples from the healthcare domain, showcasing how we can achieve the following:

  • Share patient data securely – Data mesh enables different departments within a hospital to manage their own patient data as independent domains. FGAC makes sure only authorized personnel can access specific patient records or data elements based on their roles and need-to-know basis.
  • Facilitate research and collaboration – Researchers can access de-identified patient data from various hospital domains through the data mesh architecture, enabling collaboration between multidisciplinary teams across different healthcare institutions, fostering knowledge sharing, and accelerating research and discovery. FGAC supports compliance with privacy regulations (such as HIPAA) by restricting access to sensitive data elements or allowing access only to aggregated, anonymized datasets.
  • Improve operational efficiency – Data mesh can streamline data sharing between hospitals and insurance companies, simplifying billing and claims processing. FGAC makes sure only authorized personnel within each organization can access the necessary data, protecting sensitive financial information.

Solution overview

In this post, we explore how to implement FGAC on Iceberg tables within an EMR on EKS application, using the capabilities of Lake Formation. For details on how to implement FGAC on Amazon EMR on EC2, refer to Fine-grained access control in Amazon EMR Serverless with AWS Lake Formation.

The following components play critical roles in this solution design:

  • Apache Iceberg OTF:
    • High-performance table format for large-scale analytics
    • Supports schema evolution, ACID transactions, and time travel
    • Compatible with Spark, Trino, Presto, and Flink
    • Amazon S3 Tables fully managed Iceberg tables for analytics workload
  • AWS Lake Formation:
    • FGAC for data lakes
    • Column-, row-, and cell-level security controls
  • Data mesh producers and consumers:
    • Producers: Create and serve domain-specific data products
    • Consumers: Access and integrate data products
    • Enables self-service data consumption

To demonstrate how you can use Lake Formation to implement cross-account FGAC within an EMR on EKS environment, we create tables in the AWS Glue Data Catalog in a central AWS account acting as producer and provision different user personas to reflect various roles and access levels in a separate AWS account acting as multiple consumers. Consumers can be spread across multiple accounts in real-world scenarios.

The following diagram illustrates the high-level solution architecture.

AWS Healthcare Data Architecture: FGAC using Lake Formation Integration with EMR on EKS

Figure 1: High Level Solution Architecture

To demonstrate the cross-account data sharing and data filtering with Lake Formation FGAC, the solution deploys two different Iceberg tables with varied access for different consumers. The permission mapping for consumers are with cross-account table shares and data cell filters.

It has two different teams with different levels of Lake Formation permissions to access Patients and Claims Iceberg tables. The following table summarizes the solution’s user personas.

Persona/Table Name Patients Claims

Patients Care Team

(team1 job execution role)

  • Exclude a column ssn
  • Include rows only from Texas and New York states
Full table access

Claims Care Team

(team2 job execution role)

No access Full table access

Prerequisites

This solution requires an AWS account with an AWS Identity and Access Management (IAM) power user role that can create and interact with AWS services, including Amazon EMR, Amazon EKS, AWS Glue, Lake Formation, and Amazon Simple Storage Service (Amazon S3). Additional specific requirements for each account are detailed in the relevant sections.

Clone the project

To get started, download the project either to your computer or the AWS CloudShell console:

git clone https://github.com/aws-samples/sample-emr-on-eks-fgac-iceberg
 cd sample-emr-on-eks-fgac-iceberg

Set up infrastructure in producer account

To set up the infrastructure in the producer account, you must have the following additional resources:

The setup script deploys the following infrastructure:

  • An S3 bucket to store sample data in Iceberg table format, registered as a data location in Lake Formation
  • An AWS Glue database named healthcare_db
  • Two AWS Glue tables: Patients and Claims Iceberg tables
  • A Lake Formation data access IAM role
  • Cross-account permissions enabled for the consumer account:
    • Allow the consumer to describe the database healthcare_db in the producer account
    • Allow to access the Patients table using a data cell filter, based on row-level selected state, and exclude column ssn
    • Allow full table access to the Claims table

Run the following producer_iceberg_datalake_setup.sh script to create a development environment in the producer account. Update its parameters according to your requirements:

export AWS_REGION=us-west-2
export PRODUCER_AWS_ACCOUNT=<YOUR_PRODUCER_AWS_ACCOUNT_ID> 
export CONSUMER_AWS_ACCOUNT=<YOUR_CONSUMER_AWS_ACCOUNT_ID> 
./producer_iceberg_datalake_setup.sh 
# run the clean-up script before re-run the setup if needed
./producer_clean_up.sh

Enable cross-account Lake Formation access in producer account

A consumer account ID and an EMR on EKS Engine session tag must set in the producer’s environment. It allows the consumer to access the producer’s AWS Glue tables governed by Lake Formation. Complete the following steps to enable cross-account access:

  1. Open the Lake Formation console in the producer account.
  2. Choose Application integration settings under Administration in the navigation pane.
  3. Select Allow external engines to filter data in Amazon S3 locations registered with Lake Formation.
  4. For Session tag values, enter EMR on EKS Engine.
  5. For AWS account IDs, enter your consumer account ID.
  6. Choose Save.
Comprehensive AWS Lake Formation application integration settings interface for managing third-party data access.

Figure 2: Producer Account – Lake Formation third-party engine configuration screen with session tags, account IDs, and data access permissions.

Validate FGAC setup in producer environment

To validate the FGAC setup in the producer account, check the Iceberg tables, data filter, and FGAC permission settings.

Iceberg tables

Two AWS Glue tables in Iceberg format were created by producer_iceberg_datalake_setup.sh. On the Lake Formation console, choose Tables under Data Catalog in the navigation pane to see the tables listed.

AWS Lake Formation Tables interface showing a success message for updated external data filtering settings, with a table list displaying healthcare database tables in Apache Iceberg format.

Figure 3: Lake Formation interface displaying claims and patients tables from healthcare_db with Apache Iceberg format.

The following screenshot shows an example of the patients table data.

Patients table data

Figure 4: Patients table data

The following screenshot shows an example of the claims table data.

claims table data

Figure 5: Claims table data

Data cell filter against patients table

After successfully running the producer_iceberg_datalake_setup.sh script, a new data cell filter named patients_column_row_filter was created in Lake Formation. This filter performs two functions:

  • Exclude the ssn column from the patients table data
  • Include rows where the state is Texas or New York

To view the data cell filter, choose Data filters under Data Catalog in the navigation pane of the Lake Formation console, and open the filter. Choose View permission to view the permission details.

Data cell filter

Figure 6: Column and Row level filter configuration for patients table

FGAC permissions allowing cross-account access

To view all the FGAC permissions, choose Data permissions under Permissions in the navigation pane of the Lake Formation console, and filter by the database name healthcare_db.

Make sure to revoke data permissions with the IAMAllowedPrincipals principal associated to the healthcare_db tables, because it will cause cross-account data sharing to fail, particularly with AWS Resource Access Manager (AWS RAM).

Data permissions overview

Figure 7: Lake Formation data permissions interface displaying filtered healthcare database resources with granular access controls

The following table summarizes the overall FGAC setup.

Resource Type Resource Permissions Grant Permissions
Database
healthcare_db

Describe Describe
Data Cell Filter
patients_column_row_filter

Select Select
Table
Claims

Select, Describe Select, Describe

Set up infrastructure in consumer account

To set up the infrastructure in the consumer account, you must have the following additional resources:

  • eksctl and kubectl packages must be installed
  • An IAM role in the consumer account must be a Lake Formation administrator to run consumer_emr_on_eks_setup.sh script
  • The Lake Formation admin must accept the AWS RAM resource share invites using the AWS RAM console, if the consumer account is outside of the producer’s organizational unit
RAM resource share screen

Figure 8: Consumer account – Cross-account RAM share for Lake Formation resource

The setup script deploys the following infrastructure:

  • An EKS cluster called fgac-blog with two namespaces:
    • User namespace: lf-fgac-user
    • System namespace:lf-fgac-secure
  • An EMR on EKS virtual cluster emr-on-eks-fgac-blog:
    • Set up with a security configuration emr-on-eks-fgac-sec-conifg
    • Two EMR on EKS job execution IAM roles:
      • Role for the Patients Care Team (team1): emr_on_eks_fgac_job_team1_execution_role
      • Role for Claims Care Team (team2): emr_on_eks_fgac_job_team2_execution_role
    • A query engine IAM role used by FGAC secure space: emr_on_eks_fgac_query_execution_role
  • An S3 bucket to store PySpark job scripts and logs
  • An AWS Glue local database named consumer_healthcare_db
  • Two resource links to cross-account shared AWS Glue tables: rl_patients and rl_claims
  • Lake Formation permission on Amazon EMR IAM roles

Run the following consumer_emr_on_eks_setup.sh script to set up a development environment in the consumer account. Update the parameters according to your use case:

export AWS_REGION=us-west-2 
export PRODUCER_AWS_ACCOUNT=<YOUR_PRODUCER_AWS_ACCOUNT_ID> 
export EKSCLUSTER_NAME=fgac-blog 
./consumer_emr_on_eks_setup.sh 
# run the clean-up script before re-run the setup if needed
./consumer_clean_up.sh

Enable cross-account Lake Formation access in consumer account

The consumer account must add the consumer account ID with an EMR on EKS Engine session tag in Lake Formation. This session tag will be used by EMR on EKS job execution IAM roles to access Lake Formation tables. Complete the following steps:

  1. Open the Lake Formation console in the consumer account.
  2. Choose Application integration settings under Administration in the navigation pane.
  3. Select Allow external engines to filter data in Amazon S3 locations registered with Lake Formation.
  4. For Session tag values, enter EMR on EKS Engine.
  5. For AWS account IDs, enter your consumer account ID.
  6. Choose Save.

Figure 9: Consumer Account – Lake Formation third-party engine configuration screen with session tags, account IDs, and data access permissions

Validate FGAC setup in consumer environment

To validate the FGAC setup in the producer account, check the EKS cluster, namespaces, and Spark job scripts to test data permissions.

EKS cluster

On the Amazon EKS console, choose Clusters in the navigation pane and confirm the EKS cluster fgac-blog is listed.

EKS Cluster view page

Figure 10: Consumer Account – EKS Cluster console page

Namespaces in Amazon EKS

Kubernetes uses namespaces as logical partitioning system for organizing objects such as Pods and Deployments. Namespaces also operate as a privilege boundary in the Kubernetes role-based access control (RBAC) system. Multi-tenant workloads in Amazon EKS can be secured using namespaces.

This solution creates two namespaces:

  • lf-fgac-user
  • lf-fgac-secure

The StartJobRun API uses the backend workflows to submit a Spark job’s UserComponents (JobRunner, Driver, Executors) in the user namespace, and the corresponding system components in the system namespace to accomplish the desired FGAC behaviors.

You can verify the namespaces with the following command:kubectl get namespaceThe following screenshot shows an example of the expected output.

Namespace summary page

Figure 11: EKS Cluster namespaces

Spark job script to test Patients Care Team’s data permissions

Starting with Amazon EMR version 6.6.0, you can use Spark on EMR on EKS with the Iceberg table format. For more information on how Iceberg works in an immutable data lake, see Build a high-performance, ACID compliant, evolving data lake using Apache Iceberg on Amazon EMR.

The following script is a snippet of the PySpark job that retrieves filtered data for the Claims and Patient tables:

    print("Patient Care Team PySpark job running on EMR on EKS! to query Patients and Claims tables!")
    print("This job queries Patients and Claims tables!")
    df1 = spark.sql('SELECT * FROM dev.${CONSUMER_DATABASE}.${rl_patients}')
    print("Patients tables data:")
    print("Note: Patients table is filtered on SSN column and it shows records only for Texas and New York states")
    df1.show(20)
    df2 = spark.sql('SELECT p.state,
                            c.claim_id,
                            c.claim_date, 
                            p.patient_name, 
                            c.diagnosis_code, 
                            c.procedure_code, 
                            c.amount, 
                            c.status, 
                            c.provider_id 
                    FROM dev.${CONSUMER_DATABASE}.${rl_claims} c 
                    JOIN dev.${CONSUMER_DATABASE}.${rl_patients} p
                   ON c.patient_id = p.patient_id 
                   ORDER BY p.state, c.claim_date')
    print("Show only relevant Claims data for Patients selected from Texas and New York state:")
    df2.show(20)
    print("Job Complete")
....	

Spark job script to test Claims Care Team’s data permissions

The following script is a snippet of the PySpark job that retrieves data from the Claims table:

    print("Claims Team PySpark job running on EMR on EKS to query Claims table!")
    print("Note: Claims Team has full access to Claims table!")
    df = spark.sql('SELECT * FROM     dev.${CONSUMER_DATABASE}.${rl_claims}')
    df.show(20)
....

Validate job execution roles for EMR on EKS

The Patients Care Team uses the emr_on_eks_fgac_job_team1_execution_role IAM role to execute a PySpark job on EMR on EKS. The job execution role has permission to query both the Patients and Claims tables.

The Claims Care Team uses the emr_on_eks_fgac_job_team2_execution_role IAM role to execute jobs on EMR on EKS. The job execution role only has permission to access Claims data.

Both IAM job execution roles have the following permissions:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "EmrGetCertificate",
            "Effect": "Allow",
            "Action": "emr-containers:CreateCertificate",
            "Resource": "*"
        },
        {
            "Sid": "LakeFormationManagedAccess",
            "Effect": "Allow",
            "Action": [
                "lakeformation:GetDataAccess",
                "glue:GetTable",
                "glue:GetCatalog",
                "glue:Create*",
                "glue:Update*"
            ],
            "Resource": "*"
        },
        {
            "Sid": "EmrSparkJobAccess",
            "Effect": "Allow",
            "Action": [
                "s3:PutObject",
                "s3:GetObject",
                "s3:DeleteObject",
                "s3:ListBucket"
            ],
            "Resource": [
                "arn:aws:s3:::${S3_BUCKET}*"
            ]
        }
        }
    ]
}

The following code is the job execution IAM role trust policy:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "TrustQueryEngineRoleToAssume",
            "Effect": "Allow",
            "Principal": {
                "AWS": "arn:aws:iam::$CONSUMER_ACCOUNT:role/$query_engine_role"
            },
            "Action": [
                "sts:AssumeRole",
                "sts:TagSession"
            ],
            "Condition": {
                "StringLike": {
                    "aws:RequestTag/LakeFormationAuthorizedCaller": "EMR on EKS Engine"
                }
            }
        },
        {
            "Sid": "TrustQueryEngineRoleToAssumeRoleOnly",
            "Effect": "Allow",
            "Principal": {
                "AWS": "arn:aws:iam::$CONSUMER_ACCOUNT:role/$query_engine_role"
            },
            "Action": "sts:AssumeRole"
        },
        {
            "Effect": "Allow",
            "Principal": {
                "Federated": "arn:aws:iam::$CONSUMER_ACCOUNT oidc-provider/oidc.eks.$AWS_REGION.amazonaws.com/id/xxxxx"
            },
            "Action": "sts:AssumeRoleWithWebIdentity",
            "Condition": {
                "StringLike": {
                    "oidc.eks.$AWS_REGION.amazonaws.com/id/xxxxx:sub": "system:serviceaccount:lf-fgac-user:emr-containers-sa-*-*-$CONSUMER_ACCOUNT-<hash36ofiamrole>"
                }
            }
        }
    ]
}

The following code is the query engine IAM role policy (emr_on_eks_fgac_query_execution_role-policy):

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "AssumeJobExecutionRole",
            "Effect": "Allow",
            "Action": [
                "sts:AssumeRole",
                "sts:TagSession"
            ],
            "Resource": ["arn:aws:iam::$CONSUMER_ACCOUNT:role/emr_on_eks_fgac_job_team1_execution_role",
                "arn:aws:iam::$CONSUMER_ACCOUNT:role/emr_on_eks_fgac_job_team2_execution_role"],
            "Condition": {
                "StringLike": {
                    "aws:RequestTag/LakeFormationAuthorizedCaller": "EMR on EKS Engine"
                }
            }
        },
        {
            "Sid": "AssumeJobExecutionRoleOnly",
            "Effect": "Allow",
            "Action": [
                "sts:AssumeRole"
            ],
            "Resource": [
                "arn:aws:iam::$CONSUMER_ACCOUNT:role/emr_on_eks_fgac_job_team1_execution_role",
                "arn:aws:iam::$CONSUMER_ACCOUNT:role/emr_on_eks_fgac_job_team2_execution_role"
            ]
    ]
}

The following code is the query engine IAM role trust policy:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Principal": {
                "AWS": "arn:aws:iam::$CONSUMER_ACCOUNT:root"
            },
            "Action": "sts:AssumeRole",
            "Condition": {}
        },
        {
            "Effect": "Allow",
            "Principal": {
                "Federated": "arn:aws:iam::$CONSUMER_ACCOUNT:oidc-provider/xxxxx"
            },
            "Action": "sts:AssumeRoleWithWebIdentity",
            "Condition": {
                "StringLike": {
                    "xxxxxx:sub": "system:serviceaccount:lf-fgac-secure:emr-containers-sa-*-*-$CONSUMER_ACCOUNT-<hash36ofiamrole>"
                }
            }
        }
    ]
}

Run PySpark jobs on EMR on EKS with FGAC

For more details about how to work with Iceberg tables in EMR on EKS jobs, refer to Using Apache Iceberg with Amazon EMR on EKS. Complete the following steps to run the PySpark jobs on EMR on EKS with FGAC:

  1. Run the following commands to run the patients and claims jobs:
bash /tmp/submit-patients-job.sh
bash /tmp/submit-claims-job.sh
  1. Watch the application logs from the Spark driver pod:

kubectl logs drive-pod-name -c spark-kubernetes-driver -n lf-fgac-user -f

Alternatively, you can navigate to the Amazon EMR console, open your virtual cluster, and choose the open icon next to the job to open the Spark UI and monitor the job progress.

Spark UI navigation

Figure 12: EMR on EKS job runs

View PySpark jobs output on EMR on EKS with FGAC

In Amazon S3, navigate to the Spark output logs folder:

s3://blog-emr-eks-fgac-test-<acct-id>-us-west-2-dev/spark-logs/<emr-on-eks-cluster-id>/jobs/<patients-job-id>/containers/spark-xxxxxx/spark-xxxxx-driver/stdout.gz
S3 path to view logs

Figure 13: EMR on EKS job’s stdout.gz location on S3 Bucket

The Patients Care Team PySpark job has query access to the Patients and Claims tables. The Patients table has filtered out the SSN column and only shows records for Texas and New York claim records, as specified in our FGAC setup.

The following screenshot shows the Claims table for only Texas and New York.

Claims data in consumer view

Figure 14: EMR on EKS Spark job output

The following screenshot shows the Patients table without the SSN column.

Patients data in consumer view

Figure 15: EMR on EKS Spark job output

Similarly, navigate to the Spark output log folder for the Claims Care Team job:

s3://blog-emr-eks-fgac-test-<acct-id>-us-west-2-dev/spark-logs/<emr-on-eks-cluster-id>/jobs/<claims-job-id>/containers/spark-xxxxxx/spark-xxxxx-driver/stdout.gz

As shown in the following screenshot, the Claims Care Team only has access to the Claims table, so when the job tried to access the Patients table, it received an access denied error.

Access denied for Claims team

Figure 16: EMR on EKS Spark job output

Considerations and limitations

Although the approach discussed in this post provides valuable insights and practical implementation strategies, it’s important to recognize the key considerations and limitations before you start using this feature. To learn more about using EMR on EKS with Lake Formation, refer to How Amazon EMR on EKS works with AWS Lake Formation.

Clean up

To avoid incurring future charges, delete the resources generated if you don’t need the solution anymore. Run the following cleanup scripts (change the AWS Region if necessary).Run the following script in the consumer account:

export AWS_REGION=us-west-2
export PRODUCER_AWS_ACCOUNT=<YOUR_PRODUCER_AWS_ACCOUNT_ID>
export EKSCLUSTER_NAME=fgac-blog
./consumer_clean_up.sh

Run the following script in the producer account:

export AWS_REGION=us-west-2
export PRODUCER_AWS_ACCOUNT=<YOUR_PRODUCER_AWS_ACCOUNT_ID>
export CONSUMER_AWS_ACCOUNT=<YOUR_CONSUMER_AWS_ACCOUNT_ID>
./producer_clean_up.sh

Conclusion

In this post, we demonstrated how to integrate Lake Formation with EMR on EKS to implement fine-grained access control on Iceberg tables. This integration offers organizations a modern approach to enforcing detailed data permissions within a multi-account open data lake environment. By centralizing data management in a primary account and carefully regulating user access in secondary accounts, this strategy can simplify governance and enhance security.

For more information about Amazon EMR 7.7 in reference to EMR on EKS, see Amazon EMR on EKS 7.7.0 releases. To learn more about using Lake Formation with EMR on EKS, see Enable Lake Formation with Amazon EMR on EKS.

We encourage you to explore this solution for your specific use cases and share your feedback and questions in the comments section.


About the authors

Janakiraman Shanmugam

Janakiraman Shanmugam

Janakiraman is a Senior Data Architect at Amazon Web Services . He has a focus in Data & Analytics and enjoys helping customers to solve Big data & machine learning problems. Outside of the office, he loves to be with his friends and family and spend time outdoors.

Tejal Patel

Tejal Patel

Tejal is Sr. Delivery Consultant from AWS Professional Services team, specializing in Data Analytics and ML solutions. She helps customers design scalable and innovative solutions with the AWS Cloud. Outside of her professional life, Tejal enjoys spending time with her family and friends.

Prabhakaran Thatchinamoorthy

Prabhakaran Thatchinamoorthy

Prabhakaran is a Software Engineer at Amazon Web Services, working on the EMR on EKS service. He specializes in building and operating multi-tenant data processing platforms on Kubernetes at scale. His areas of interest include open-source batch and streaming frameworks, data tooling, and DataOps.

Unlock real-time data insights with schema evolution using Amazon MSK Serverless, Iceberg, and AWS Glue streaming

Post Syndicated from Nitin Kumar original https://aws.amazon.com/blogs/big-data/unlock-real-time-data-insights-with-schema-evolution-using-amazon-msk-serverless-iceberg-and-aws-glue-streaming/

Efficient real-time synchronization of data within data lakes present challenges. Any data inaccuracies or latency issues can significantly compromise analytical insights and subsequent business strategies. Organizations increasingly require synchronized data in near real-time to extract actionable intelligence and respond promptly to evolving market dynamics. Additionally, scalability remains a concern for data lake implementations, which must accommodate expanding volumes of streaming data and maintain optimal performance without incurring high operational costs.

Schema evolution is the process of modifying the structure (schema) of a data table to accommodate changes in the data over time, such as adding or removing columns, without disrupting ongoing operations or requiring a complete data rewrite. Schema evolution is vital in streaming data environments for several reasons. Unlike batch processing, streaming pipelines operate continuously, ingesting data in real time from sources that are actively serving production applications. Source systems naturally evolve over time as businesses add new features, refine data models, or respond to changing requirements. Without proper schema evolution capabilities, even minor changes to source schemas can force streaming pipeline shutdowns, requiring developers to manually reconcile schema differences and rebuild tables.

Such disruptions reduce the core value proposition of streaming architectures—continuous, low-latency data processing. Organizations can maintain uninterrupted data flows and keep source systems evolving independently by using the seamless schema evolution provided by Apache Iceberg. This reduces operational friction and maintains the availability of real-time analytics and applications even as underlying data structures change.

Apache Iceberg is an open table format, delivering essential capabilities for streaming workloads, including robust schema evolution support. This critical feature enables table schemas to adapt dynamically as source database structures evolve, maintaining operational continuity. Consequently, when database columns undergo additions, removals, or modifications, the data lake accommodates these changes seamlessly without requiring manual intervention or risking data inconsistencies.
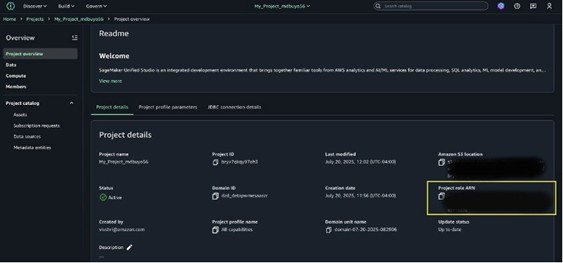
Our comprehensive solution showcases an end-to-end real-time CDC pipeline that enables immediate processing of data modifications from Amazon Relational Database Service (Amazon RDS) for MySQL, streaming altered records directly to AWS Glue streaming jobs using Amazon Managed Streaming for Apache Kafka (Amazon MSK) Serverless. These jobs continually process incoming changes and update Iceberg tables on Amazon Simple Storage Service (Amazon S3) so that the data lake reflects the current state of the operational database environment in real time. By using Apache Iceberg’s comprehensive schema evolution support, our ETL pipeline automatically adapts to database schema modifications, providing data lake consistency and currentness without manual intervention. This approach combines complete process control with instantaneous analytics on operational data, eliminating traditional latency, and future-proofs the solution to address evolving organizational data needs. The architecture’s inherent flexibility facilitates adaptation to diverse use cases requiring immediate data insights.

Solution overview

To effectively address streaming challenges, we propose an architecture using Amazon MSK Serverless, a comprehensive managed Apache Kafka service that autonomously provisions and scales computational and storage resources. This solution offers a frictionless mechanism for ingesting and processing streaming data without the complexity of capacity management. Our implementation uses Amazon MSK Connect with the Debezium MySQL connector to capture and stream database modifications in real time. Rather than employing traditional batch processing methodologies, we implement an AWS Glue streaming job that directly consumes data from Kafka topics, processes CDC events as they occur, and writes transformed data to Apache Iceberg tables on Amazon S3.
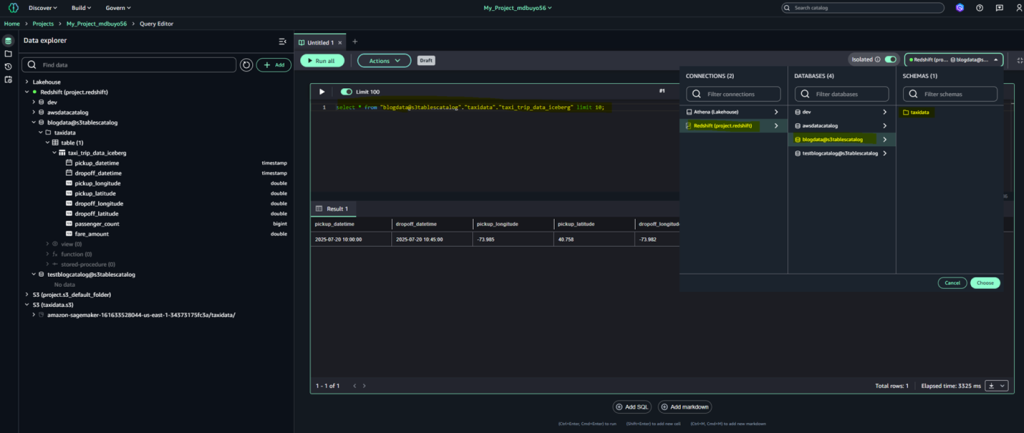
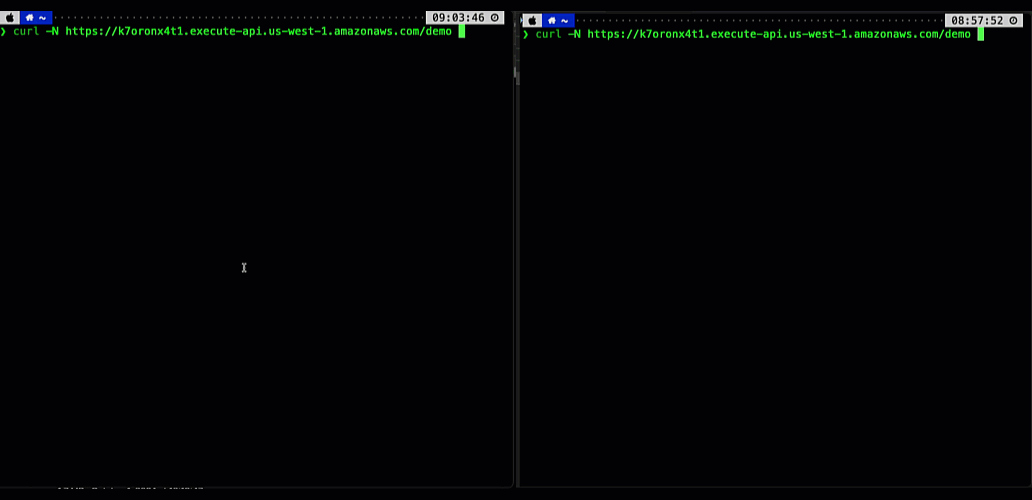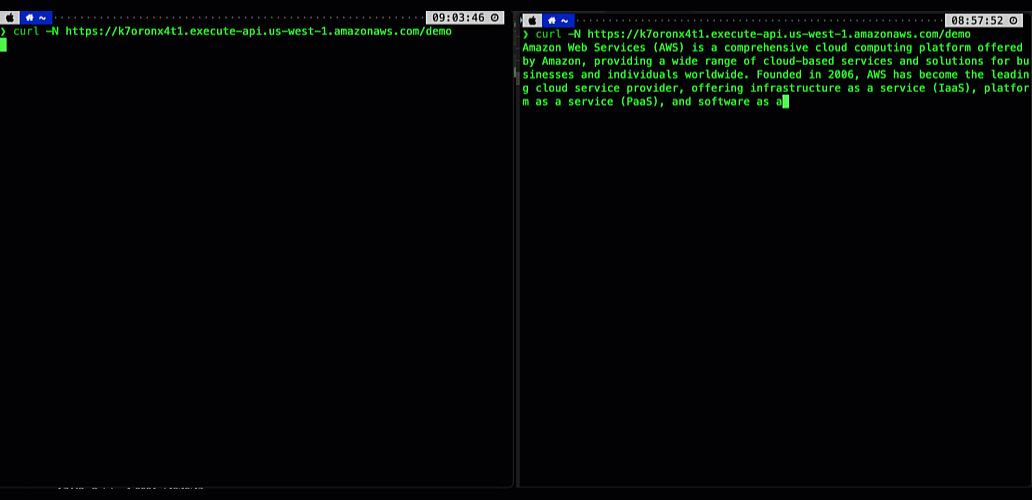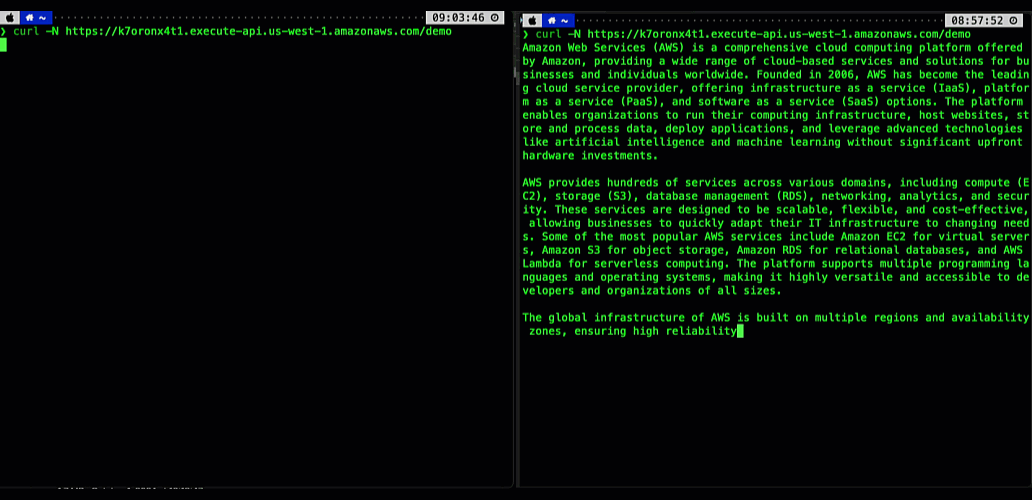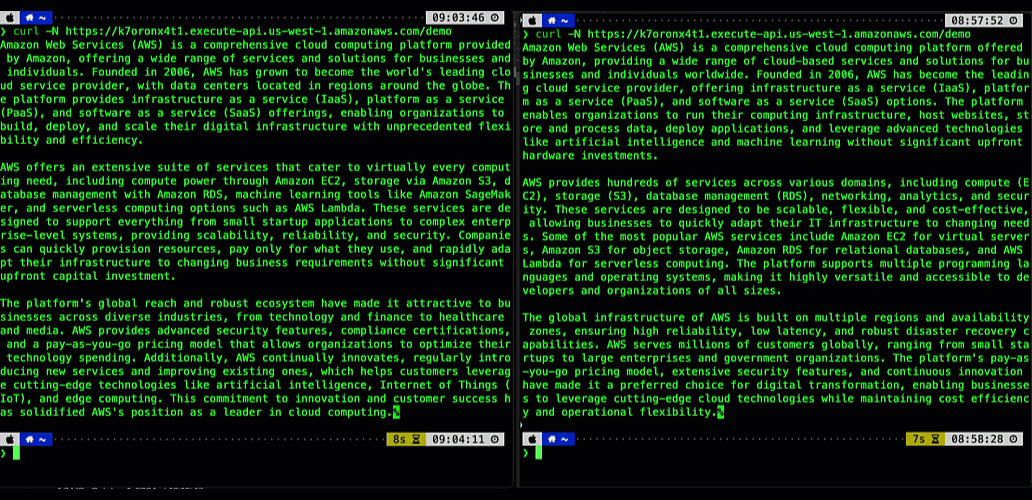
The workflow consists of the following:

  1. Data flows from Amazon RDS through Amazon MSK Connect using the Debezium MySQL connector to Amazon MSK Serverless. This represents a CDC pipeline that captures database changes from the relational database and streams them to Kafka.
  2. From Amazon MSK Serverless, the data then moves to AWS Glue job, which processes the data and stores it in Amazon S3 as Iceberg tables. The AWS Glue job interacts with the AWS Glue Data Catalog to maintain metadata about the datasets.
  3. Analyze the data using the serverless interactive query service Amazon Athena, which can be used to query the iceberg table created in Data Catalog. This allows for interactive data analysis without managing infrastructure.

The following diagram illustrates the architecture that we implement through this post. Each number corresponds to the preceding list and shows major components that you implement.

Prerequisites

Before getting started, make sure you have the following:

  • An active AWS account with billing enabled
  • An AWS Identity and Access Management (IAM) user with specific permissions to create and manage resources, such as a virtual private cloud (VPC), subnet, security group, IAM roles, NAT gateway, internet gateway, Amazon Elastic Compute Cloud (Amazon EC2) client, MSK Serverless, MSK Connector and its plugin AWS Glue job, and S3 buckets.
  • Sufficient VPC capacity in your chosen AWS Region.

For this post, we create the solution resources in the US East (N. Virginia) – us-east-1 Region using AWS CloudFormation templates. In the following sections, we show you how to configure your resources and implement the solution.

Configuring CDC and processing using AWS CloudFormation

In this post, you use the CloudFormation template vpc-msk-mskconnect-rds-client-gluejob.yaml. This template sets up the streaming CDC pipeline resources such as a VPC, subnet, security group, IAM roles, NAT, internet gateway, EC2 client, MSK Serverless, MSK Connect, Amazon RDS, S3 buckets, and AWS Glue job.

To create the solution resources for the CDC pipeline, complete the following steps:

  1. Launch the stack vpc-msk-mskconnect-rds-client-gluejob.yaml using the CloudFormation template:
  2. Provide the parameter values as listed in the following table.

    A B C
    1 Parameters Description Sample value
    2 EnvironmentName An environment name that is prefixed to resource names. msk-iceberg-cdc-pipeline
    3 DatabasePassword Database admin account password. ****
    4 InstanceType MSK client EC2 instance type. t2.micro
    5 LatestAmiId Latest AMI ID of Amazon Linux 3 for ec2 instance. You can use the default value. /aws/service/ami-amazon-linux-latest/al2023-ami-kernel-default-x86_64
    6 VpcCIDR IP range (CIDR notation) for this VPC. 10.192.0.0/16
    7 PublicSubnet1CIDR IP range (CIDR notation) for the public subnet in the first Availability Zone. 10.192.10.0/24
    8 PublicSubnet2CIDR IP range (CIDR notation) for the public subnet in the second Availability Zone. 10.192.11.0/24
    9 PrivateSubnet1CIDR IP range (CIDR notation) for the private subnet in the first Availability Zone. 10.192.20.0/24
    10 PrivateSubnet2CIDR IP range (CIDR notation) for the private subnet in the second Availability Zone. 10.192.21.0/24
    11 NumberOfWorkers Number of workers for AWS Glue streaming job. 3
    12 GlueWorkerType Worker type for AWS Glue streaming job. For example, G.1X. G.1X
    13 GlueDatabaseName Name of the AWS Glue Data Catalog database. glue_cdc_blogdb
    14 GlueTableName Name of the AWS Glue Data Catalog table. iceberg_cdc_tbl

The stack creation process can take approximately 25 minutes to complete. You can check the Outputs tab for the stack after the stack is created, as shown in the following screenshot.

Following the successful deployment of the CloudFormation stack, you now have a fully operational Amazon RDS database environment. The database instance contains the salesdb database with the customer table populated with 30 data records.

These records have been streamed to the Kafka topic through the Debezium MySQL connector implementation, establishing a reliable CDC pipeline. With this foundation in place, proceed to the next phase of the data architecture: near real-time data processing using the AWS Glue streaming job.

Run the AWS Glue streaming job

To transfer the data load from the Kafka topic (created by the Debezium MySQL connector for database table customer) to the Iceberg table, run the AWS Glue streaming job configured by the CloudFormation setup. This process will migrate all existing customer data from the source database table to the Iceberg table. Complete the following steps:

  1. On the CloudFormation console, choose the stack vpc-msk-mskconnect-rds-client-gluejob.yaml
  2. On the Outputs tab, retrieve the name of the AWS Glue streaming job from the GlueJobName row. In the following screenshot, the name is IcebergCDC-msk-iceberg-cdc-pipeline.
  3. On the AWS Glue console, choose ETL jobs in the navigation pane.
  4. Search for the AWS Glue job named IcebergCDC-msk-iceberg-cdc-pipeline.
  5. Choose the job name to open its details page.
  6. Choose Run to start the job. On the Runs tab, confirm if the job ran without failure.

You need to wait approximately 2 minutes for the job to process before continuing. This pause allows the jobrun to fully process records from the Kafka topic (initial load) and create the Iceberg table.

Query the Iceberg table using Athena

After the AWS Glue streaming job has successfully started and the Iceberg table has been created in the Data Catalog, follow these steps to validate the data using Athena:

  1. On the Athena console, navigate to the query editor.
  2. Choose the Data Catalog as the data source.
  3. Choose the database glue_cdc_blogdb.
  4. To validate the data, enter the following query to preview the data and find the total count:
    SELECT id, name, mktsegment FROM "glue_cdc_blogdb"."iceberg_cdc_tbl" order by id desc limit 40;
    
    SELECT count(*) as total_rows FROM "glue_cdc_blogdb"."iceberg_cdc_tbl";

    The following screenshot shows the output of the example query.

After performing the preceding steps, you’ve established a complete near real-time data processing pipeline by running an AWS Glue streaming job that transfers data from Kafka topics to an Apache Iceberg table, then verified the successful data migration by querying the results through Amazon Athena.

Upload incremental (CDC) data for further processing

Now that you’ve successfully completed the initial full data load, it’s time to focus on the dynamic aspects of the data pipeline. In this section, we explore how the system handles ongoing data modifications such as insertions, updates, and deletions in Amazon RDS for MySQL database. These changes won’t go unnoticed. Our Debezium MySQL connector stands ready to capture each modification event, transforming database changes into a continuous stream of data. Working in tandem with our AWS Glue streaming job, this architecture is designed to promptly process and propagate every change in our source database through our data pipeline.Let’s see this real-time data synchronization mechanism in action, demonstrating how our modern data infrastructure maintains consistency across systems with minimal latency. Follow these steps:

  1. On the Amazon EC2 console, access the EC2 instance that you created using the CloudFormation template named as KafkaClientInstance.
  2. Log in to the EC2 instance using AWS Systems Manager Agent (SSM Agent). Select the instance named as KafkaClientInstance and then choose Connect.
  3. Enter the following commands to insert the data into the RDS table. Use the same database password you entered when you created the CloudFormation stack.
    sudo su - ec2-user
    RDS_AURORA_ENDPOINT=`aws rds describe-db-instances --region us-east-1 | jq -r '.DBInstances[] | select(.DBName == "salesdb") | .Endpoint.Address'`
    mysql -f -u master -h $RDS_AURORA_ENDPOINT  --password

  4. Now perform the insert, update, and delete in the CUSTOMER table.
    use salesdb;
    
    INSERT INTO customer VALUES(31, 'Customer Name 31', 'Market segment 31');
    INSERT INTO customer VALUES(32, 'Customer Name 32', 'Market segment 32');
    
    UPDATE customer SET name='Customer Name update 29', mktsegment='Market segment update 29' WHERE id = 29;
    UPDATE customer SET name='Customer Name update 30', mktsegment='Market segment update 30' WHERE id = 30;
    
    DELETE FROM customer WHERE id = 27;
    DELETE FROM customer WHERE id = 28;
    

  5. Validate the data to verify the insert, update, and delete records in the Iceberg table from Athena, as shown in the following screenshot.

After performing the preceding steps, you’ve learned how our CDC pipeline handles ongoing data modifications by performing insertions, updates, and deletions in the MySQL database and verifying how these changes are automatically captured by Debezium MySQL connector, streamed through Kafka, and reflected in the Iceberg table in near real time.

Schema evolution: Adding new columns to the Iceberg table

The schema evolution mechanism in this implementation provides an automated approach to detecting and adding new columns from incoming data to existing Iceberg tables. Although Iceberg inherently supports robust schema evolution capabilities (including adding, dropping, and renaming columns, updating types, and reordering), this code specifically automates the column addition process for streaming environments. This automation uses Iceberg’s underlying schema evolution capabilities, which guarantee correctness through unique column IDs that ensure new columns never read existing values from another column. By handling column additions programmatically, the system reduces operational overhead in streaming pipelines where manual schema management would create bottlenecks. However, dropping and renaming columns, updating types, and reordering still required manual intervention.

When new data arrives through Kafka streams, the handle_schema_evolution() function orchestrates a four-step process to ensure seamless table schema updates.

  1. It analyzes the incoming batch DataFrame to infer its schema structure, cataloging all column names and their corresponding data types.
  2. It retrieves the existing Iceberg table’s schema from the AWS Glue catalog to establish a baseline for comparison.
  3. The system then performs a schema comparison using method compare_schemas() between batch schema with existing table schema.
    1. If the incoming frame contains fewer columns than the catalog table, no action is taken.
    2. It identifies any new columns present in the incoming data that don’t exist in the current table structure and returns a list of new columns that need to be added.
    3. New columns will be added at the last.
    4. Handle type evolution isn’t supported. If needed, you can handle the same at comment # Handle type evolution in the compare_schemas() method.
    5. If the destination table has columns that are dropped in the source table, it doesn’t drop those columns. If that is required for your use case, you can use drop column manually using ALTER TABLE ... DROP COLUMN.
    6. Renaming the column isn’t supported. To rename the column use case, manually evolve the schema using ALTER TABLE … RENAME COLUMN.
  4. Finally, if new columns are discovered, the function executes ALTER TABLE … ADD COLUMN statements to evolve the Iceberg table schema, adding the new columns with their appropriate data types.

This approach eliminates the need for manual schema management and prevents data pipeline failures that would typically occur when encountering unexpected fields in streaming data. The implementation also includes proper error handling and logging to track schema evolution events, making it particularly valuable for environments where data structures frequently change.

def infer_schema_from_batch(batch_df):
    """
    Infer schema from the batch DataFrame
    Returns a dictionary with column names and their inferred types
    """
    schema_dict = {}
    for field in batch_df.schema.fields:
        schema_dict[field.name] = field.dataType
    return schema_dict

def get_existing_table_schema(spark, table_identifier):
    """
    Read the existing table schema from the Iceberg table
    Returns a dictionary with column names and their types
    """
    try:
        existing_df = spark.table(table_identifier)
        schema_dict = {}
        for field in existing_df.schema.fields:
            schema_dict[field.name] = field.dataType
        return schema_dict
    except Exception as e:
        print(f"Error reading existing table schema: {e}")
        return {}

def compare_schemas(batch_schema, existing_schema):
    """
    Compare batch schema with existing table schema
    Returns a list of new columns that need to be added
    """
    new_columns = []
    
    for col_name, col_type in batch_schema.items():
        if col_name not in existing_schema:
            new_columns.append((col_name, col_type))
        elif existing_schema[col_name] != col_type:
            # Handle type evolution if needed
            print(f"Warning: Column {col_name} type mismatch - existing: {existing_schema[col_name]}, new: {col_type}")
    
    return new_columns

def spark_type_to_sql_string(spark_type):
    """
    Convert Spark DataType to SQL string representation for ALTER TABLE
    """
    type_mapping = {
        'IntegerType': 'INT',
        'LongType': 'BIGINT',
        'StringType': 'STRING',
        'BooleanType': 'BOOLEAN',
        'DoubleType': 'DOUBLE',
        'FloatType': 'FLOAT',
        'TimestampType': 'TIMESTAMP',
        'DateType': 'DATE'
    }
    
    type_name = type(spark_type).__name__
    return type_mapping.get(type_name, 'STRING')

def evolve_table_schema(spark, table_identifier, new_columns):
    """
    Alter the Iceberg table to add new columns
    """
    if not new_columns:
        return
    
    try:
        for col_name, col_type in new_columns:
            sql_type = spark_type_to_sql_string(col_type)
            alter_sql = f"ALTER TABLE {table_identifier} ADD COLUMN {col_name} {sql_type}"
            print(f"Executing schema evolution: {alter_sql}")
            spark.sql(alter_sql)
            print(f"Successfully added column {col_name} with type {sql_type}")
    except Exception as e:
        print(f"Error during schema evolution: {e}")
        raise e

def handle_schema_evolution(spark, batch_df, table_identifier):
    """
    schema evolution steps
    1. Infer schema from batch DataFrame
    2. Read existing table schema
    3. Compare schemas and identify new columns
    4. Alter table if schema evolved
    """
    # Step 1: Infer schema from batch DataFrame
    batch_schema = infer_schema_from_batch(batch_df)
    print(f"Batch schema: {batch_schema}")
    
    # Step 2: Read existing table schema
    existing_schema = get_existing_table_schema(spark, table_identifier)
    print(f"Existing table schema: {existing_schema}")
    
    # Step 3: Compare schemas
    new_columns = compare_schemas(batch_schema, existing_schema)
    
    # Step 4: Evolve schema if needed
    if new_columns:
        print(f"Schema evolution detected. New columns: {new_columns}")
        evolve_table_schema(spark, table_identifier, new_columns)
        return True
    else:
        print("No schema evolution needed")
        return False

In this section, we demonstrate how our system handles structural changes to the underlying data model by adding a new status column to the customer table and populating it with default values. Our architecture is designed to seamlessly propagate these schema modifications throughout the pipeline so that downstream analytics and processing capabilities remain uninterrupted while accommodating the enhanced data model. This flexibility is essential for maintaining a responsive, business-aligned data infrastructure that can evolve alongside changing organizational needs.

  1. Add a new status column to the customer table and populate it with default values as Green.
    use salesdb;
    
    ALTER TABLE customer ADD COLUMN status VARCHAR(20) NOT NULL;
    
    UPDATE customer SET status = 'Green';
    

  2. Use the Athena console to validate the data and schema evolution, as shown in the following screenshot.

When schema evolution occurs in an Iceberg table, the metadata.json file undergoes specific updates to track and manage these changes. In job when schema evolution detected, it ran the following query to evolve the schema for the Iceberg table.

ALTER TABLE glue_catalog.glue_cdc_blogdb.iceberg_cdc_tbl ADD COLUMN status string

We checked the metadata.json file in Amazon S3 for iceberg table location, and the following screenshot shows how the schema evolved.

We now explain how our implementation handles schema evolution by automatically detecting and adding new columns from incoming data streams to existing Iceberg tables. The system employs a four-step process that analyzes incoming data schemas, compares them with existing table structures, identifies new columns, and executes the necessary ALTER TABLE statements to evolve the schema without manual intervention, though certain schema changes still require manual handling.

Clean up

To clean up your resources, complete the following steps:

  1. Stop the running AWS Glue streaming job:
    1. On the AWS Glue console, choose ETL jobs in the navigation pane.
    2. Search for the AWS Glue job named IcebergCDC-msk-iceberg-cdc-pipeline.
    3. Choose the job name to open its details page.
    4. On the Runs tab, select running jobrun and choose Stop job run. Confirm that the job stopped successfully.
  2. Remove the AWS Glue database and table:
    1. On the AWS Glue console, choose Tables in the navigation pane, select iceberg_cdc_tbl, and choose Delete.
    2. Choose Databases in the navigation pane, select glue_cdc_blogdb, and choose Delete.
  3. Delete the CloudFormation stack vpc-msk-mskconnect-rds-client-gluejob.yaml.

Conclusion

This post showcases a solution that businesses can use to access real-time data insights without the traditional delays between data creation and analysis. By combining Amazon MSK Serverless, Debezium MySQL connector, AWS Glue streaming, and Apache Iceberg tables, the architecture captures database changes instantly and makes them immediately available for analytics through Amazon Athena. A standout feature is the system’s ability to automatically adapt when database structures change—such as adding new columns—without disrupting operations or requiring manual intervention. This eliminates the technical complexity typically associated with real-time data pipelines and provides business users with the most current information for decision-making, effectively bridging the gap between operational databases and analytical systems in a cost-effective, scalable way.


About the Authors

Nitin Kumar

Nitin Kumar

Nitin is a Cloud Engineer (ETL) at AWS, specializing in AWS Glue. With a decade of experience, he excels in aiding customers with their big data workloads, focusing on data processing and analytics. In his free time, he likes to watch movies and spend time with his family.

Shubham Purwar

Shubham Purwar

Shubham is an Analytics Specialist Solutions Architect at AWS. He helps organizations unlock the full potential of their data by designing and implementing scalable, secure, and high-performance analytics solutions on AWS. In his free time, Shubham loves to spend time with his family and travel around the world.

Noritaka Sekiyama

Noritaka Sekiyama

Noritaka is a Principal Big Data Architect on the AWS Glue team. He works based in Tokyo, Japan. He is responsible for building software artifacts to help customers. In his spare time, he enjoys cycling with his road bike.

Upgrade from Amazon Redshift DC2 node type to Amazon Redshift Serverless
Post Syndicated from Nita Shah original https://aws.amazon.com/blogs/big-data/upgrade-from-amazon-redshift-dc2-node-type-to-amazon-redshift-serverless/

Amazon Redshift is a fully managed, petabyte-scale, cloud data warehouse service. You can use Amazon Redshift to run complex queries against petabytes of structured and semi-structured data quickly and efficiently, integrating seamlessly with other AWS services.
Amazon Redshift Serverless helps you run and scale analytics in seconds without having to set up, manage, or scale data warehouse infrastructure. It automatically provisions data warehouse capacity and intelligently scales the underlying resources to deliver fast performance for demanding workloads and you pay only for the compute capacity you use. Additionally, with Amazon Redshift managed storage, you can further optimize your data warehouse by scaling storage and compute independently and you pay only for the storage you use.

Upgrading your data warehouse from Amazon Redshift dense compute (DC2) instances to Amazon Redshift Serverless unlocks these advantages and provides an enhanced user experience and simplified operations, offering a more efficient, scalable solution for data analytics.

In this post, we show you the upgrade process from DC2 instances to Amazon Redshift Serverless. We’ll cover:

  1. Assessing your current setup and determining if an upgrade is right for you
  2. Planning and preparing for the upgrade
  3. Step-by-step instructions for the upgrade process
  4. Post-upgrade optimization and best practices

Why upgrade to Amazon Redshift Serverless

By using Amazon Redshift Serverless, you can run and scale analytics without managing data warehouse infrastructure. When you upgrade from DC2 instances to Amazon Redshift Serverless, you get the following benefits:

  • Simplified operations: Access and analyze data without needing to set up, tune, and manage compute clusters.
  • Automatic performance optimization: Deliver consistently high performance and simplified operations for demanding and volatile workloads with automatic scaling and AI driven scaling and optimization.
  • Pay-as-you-go pricing: The flexible pricing structure charges you only during active usage; you pay only for what you use.
  • Online maintenance: Amazon Redshift Serverless automatically manages system updates and patches without requiring maintenance windows, helping to facilitate seamless operation of your data warehouse.
  • Decoupled storage and compute: Control costs by scaling and paying for compute and storage separately with Amazon Redshift managed storage.
  • Access to new capabilities: Use advanced features including data sharing writes, Redshift Streaming Ingestion, zero-ETL, and other capabilities.

Sizing guidance

To upgrade from DC2 to Amazon Redshift Serverless, you need to understand the size equivalency. The following table shows suggested sizing configurations when upgrading from the DC2 node type.

Note that availability of Redshift Processing Unit (RPU) configurations varies by AWS Region.

Existing node type Existing number of nodes Amazon Redshift Serverless upgrade
DC2.large 1–4 Start with 4 RPUs
DC2.large 5–7 Start with 8 RPUs
DC2.large 8–32 Add 8 RPUs per 8 nodes of DC2.large
DC2.8xlarge 2–32 Add 16 RPUs per node (up to a maximum of 1,024 RPUs)

These sizing estimates provide a flexible starting point tailored to help you make the most of Amazon Redshift Serverless. The ideal configuration for your needs will depend on factors such as your desired balance of cost and performance and the specific latency and throughput requirements of your workload. To further optimize the sizing based on your specific requirements, you can use one or more of following approaches:

  • Test your workload beforehand: Before migrating to Amazon Redshift Serverless, evaluate your workload’s performance requirements in a non-production environment. The Amazon Redshift Test Drive utility simplifies this process by simulating your production workloads across different serverless configurations. You can use the results to help identify the optimal balance between performance and cost and make informed decisions about your configuration. For step-by-step guidance on using the Test Drive utility for DC2 to Serverless upgrades, see the Amazon Redshift Migration Workshop. Running these performance tests before migration helps you to identify any necessary adjustments to your configuration before deploying to production
  • Monitor in production: After you’ve deployed your workload, closely monitor the performance and resource utilization for over a period of time that represents your typical workloads. Based on the observed metrics, you can then scale the resources up or down as needed to achieve the best balance of performance and cost.
  • AI-driven scaling and optimization: Consider using Amazon Redshift Serverless with AI-driven scaling and optimization to automatically size Amazon Redshift Serverless for your workload needs.

A methodical approach to sizing validation, combining both pre-production testing and ongoing production monitoring, helps ensure your Amazon Redshift Serverless configuration aligns with your workload.

Upgrade to Amazon Redshift Serverless

To upgrade to Amazon Redshift Serverless, you can use a snapshot restore to move directly from Amazon Redshift to Amazon Redshift Serverless, as shown in the following figure. A snapshot restore restores data and objects in addition to users and their associated permissions, configurations, and schema structures. By using snapshot restore for migration, you can validate the target Amazon Redshift Serverless warehouses without impacting your production Amazon Redshift DC2 cluster. You can also use snapshot restore to migrate your Amazon Redshift DC2 workloads to different Regions or Availability Zones.

Prerequisites to migrate using a snapshot restore

  1. Create an Amazon Redshift Serverless workgroup with a namespace. For more information, see creating workgroup with a namespace.
  2. Amazon Redshift Serverless is encrypted by default. Amazon Redshift Serverless also supports changing the AWS KMS key for the namespace so you can adhere to your organization’s security policies.
  3. Verify that the Amazon Redshift Serverless namespace you’re trying to restore to is attached to an Amazon Redshift Serverless workgroup.
  4. To restore from a provisioned Amazon Redshift cluster to Amazon Redshift Serverless, the AWS Identity and Access Management (IAM) user or role must have the following permissions: redshift-serverless:RestoreFromSnapshot, CreateNamespace, and CreateWorkgroup. For more information, see Amazon Redshift Serverless restore.

Upgrade using the console

Use the following steps in the AWS Management Console for Amazon Redshift to upgrade your DC2 cluster to Amazon Redshift Serverless using the snapshot restore method.

  1. On the Redshift console, choose Clusters in the navigation pane. Select your cluster and then choose Maintenance.
  2. Choose Create snapshot to create a manual snapshot of the existing Amazon Redshift provisioned cluster.
  3. Enter a snapshot identifier, select the snapshot retention period, and then choose Create snapshot.
  4. Select the snapshot you want to restore to Amazon Redshift Serverless from the list and then choose Restore snapshot and select Restore to serverless namespace.
  5. Under Select namespace, select your target serverless namespace from the dropdown list and then choose Restore.
  6. The restoration time will vary based on your data volume.
  7. After the restoration completes, verify your data migration by connecting to your Amazon Redshift Serverless workspace using either the Amazon Redshift Query Editor v2 or your preferred SQL client.

For more information, see Creating a snapshot of your provisioned cluster.

Upgrade using the AWS CLI

Use the following steps in the AWS Command Line Interface (AWS CLI) to upgrade your DC2 cluster to Amazon Redshift Serverless using the snapshot restore method.

  1. Create a snapshot from the source cluster:
    aws redshift create-cluster-snapshot --cluster-identifier <your-dc2-cluster-id>  --snapshot-identifier <your-snapshot-name>

  2. Verify that the snapshot exists:
    aws redshift describe-cluster-snapshots --snapshot-identifier <your-snapshot-name>

  3. Restore the snapshot to your Amazon Redshift Serverless namespace:
    aws redshift-serverless restore-from-snapshot --snapshot-arn "arn:aws:redshift:<your-region>:<your-account-number>:snapshot:<source-cluster-id>/<your-snapshot-name>" --namespace-name <your-serverless-namespace> --workgroup-name <your-serverless-workgroup> --region <your-region>

For more information, see Restore from cluster snapshot using AWS CLI.

Best practices for upgrading to Amazon Redshift Serverless

The following are recommended best practices when upgrading from Amazon Redshift to Amazon Redshift Serverless.

  • Pre-upgrade:
  • Post-upgrade:
    • Update existing connections: When you migrate to Amazon Redshift Serverless, a new endpoint will be created. Update any existing connections to business intelligence and other reporting tools.
    • Observability and monitoring: If you have any data monitoring tools using systems views, verify that there are no open or empty transactions. It’s important as a best practice to end transactions. If you don’t end or roll back open transactions, Amazon Redshift Serverless will continue to use RPUs for those transactions.
    • Access: When using IAM authentication with dbUser and dbGroups, your applications can access the database using the GetCredentials API. For more information, see Connecting using IAM.
    • System views: Review the list of unified system views available in Amazon Redshift Serverless.

If your workloads aren’t suited for Amazon Redshift Serverless because of their nature or any of the considerations listed in Considerations when using Amazon Redshift Serverless, you can upgrade to Amazon Redshift RA3 instances by following the RA3 sizing guidance.

Cost considerations

In this section, we provide information to help you understand and manage your Amazon Redshift Serverless costs.

  • You can reduce your serverless computing costs by reserving capacity in advance when you have predictable usage patterns.
  • Amazon Redshift Serverless automatically adjusts capacity based on workload. By setting a maximum RPU limit, you can control costs by capping how much the system can scale up.
  • Amazon Redshift Serverless uses RPUs as a compute unit. While it starts with a default of 128 RPUs, you can adjust the base RPU anywhere from 4 to 1,024 RPUs to match your specific workload needs and SLA requirement. For more information, see Billing for Amazon Redshift Serverless.
  • Amazon Redshift Serverless automatically creates recovery points every 30 minutes or whenever 5 GB of data changes per node occur, whichever happens first. The minimum interval between recovery points is 15 minutes. All recovery points are retained for 24 hours by default.

If you need to preserve backups for a longer period, you can create manual backups. Manual backups will incur additional storage costs.

Clean up

To avoid incurring future charges, delete the Amazon Redshift Serverless instance or provisioned data warehouse cluster created as part of the prerequisite steps. For more information, see Deleting a workgroup and Shutting down and deleting a cluster.

Conclusion

In this post, we discussed the benefits of upgrading Amazon Redshift DC2 instances to Amazon Redshift Serverless, in addition to the various options for upgrading and some best practices. It is essential to determine the target Amazon Redshift Serverless configuration and validate it using Amazon Redshift Test Drive utility in test and development environments before upgrading.

Get started upgrading to Amazon Redshift Serverless today by implementing the guidance in this post. If you have questions or need assistance, contact AWS Support forarchitectural and design guidance, in addition to support for proofs of concept and implementation.


About the authors

Nita Shah

Nita Shah

Nita is a Senior Analytics Specialist Solutions Architect at AWS based out of New York. She has been building data warehouse solutions for over 20 years and specializes in Amazon Redshift. She is focused on helping customers design and build enterprise-scale well-architected analytics and decision support platforms.

Ricardo Serafim

Ricardo Serafim

Ricardo is a Senior Analytics Specialist Solutions Architect at AWS. He has been helping companies with Data Warehouse solutions since 2007.

Bryan Cottle

Bryan Cottle

Bryan is a Senior Technical Product Manager at Amazon Web Services. He’s passionate about analytical databases, specializing in Amazon Redshift where he helps customers optimize costs, navigate pricing strategies, and successfully manage their database migrations

Stifel’s approach to scalable Data Pipeline Orchestration in Data Mesh

Post Syndicated from Srinivas Kandi, Hossein Johari, Ahmad Rawashdeh, Lei Meng original https://aws.amazon.com/blogs/big-data/stifels-approach-to-scalable-data-pipeline-orchestration-in-data-mesh/

This is a guest post by Hossein Johari, Lead and Senior Architect at Stifel Financial Corp, Srinivas Kandi and Ahmad Rawashdeh, Senior Architects at Stifel, in partnership with AWS.

Stifel Financial Corp, a diversified financial services holding company is expanding its data landscape that requires an orchestration solution capable of managing increasingly complex data pipeline operations across multiple business domains. Traditional time-based scheduling systems fall short in addressing the dynamic interdependencies between data products, requires event-driven orchestration. Key challenges include coordinating cross-domain dependencies, maintaining data consistency across business units, meeting stringent SLAs, and scaling effectively as data volumes grow. Without a flexible orchestration solution, these issues can lead to delayed business operations and insights, increased operational overhead, and heightened compliance risks due to manual interventions and rigid scheduling mechanisms that cannot adapt to evolving business needs.

In this post, we walk through how Stifel Financial Corp, in collaboration with AWS ProServe, has addressed these challenges by building a modular, event-driven orchestration solution using AWS native services that enables precise triggering of data pipelines based on dependency satisfaction, supporting near real-time responsiveness and cross-domain coordination.

Data platform orchestration

Stifel and AWS technology teams identified several key requirements that would guide their solution architecture to overcome the above listed challenges along with traditional data pipeline orchestration.

Coordinated pipeline execution across multiple data domains based on events

  • The orchestration solution must support triggering data pipelines across multiple business domains based on events such as data product publication or completion of upstream jobs.

Smart dependency management

  • The solution should intelligently manage pipeline dependencies across domains and accounts.
  • It must ensure that downstream pipelines wait for all necessary upstream data products, regardless of which team or AWS account owns them.
  • Dependency logic should be dynamic and adaptable to changes in data availability.

Business-aligned configuration

  • A no-code architecture should allow business users and data owners to define pipeline dependencies and triggers using metadata.
  • All changes to dependency configurations should be version-controlled, traceable, and auditable.

Scalable and flexible architecture

  • The orchestration solution should support hundreds of pipelines across multiple domains without performance degradation.
  • It should be easy to onboard new domains, define new dependencies, and integrate with existing data mesh components.

Visibility and monitoring

  • Business users and data owners should have access showing pipeline status, including success, failure, and progress.
  • Alerts and notifications should be sent when issues occur, with clear diagnostics to support rapid resolution.

Example Scenario

The following below illustrates a cross-domain data dependency scenario, where a data product in domain (D1 and D2) relies on the prompt refresh of data products from other domains, each operating on distinct schedules. Upon completion, these upstream data products emit refresh events that automatically trigger the execution of a dependent downstream pipeline.

  • Dataset DS1 for Domain D1 depends on RD1 and RD2 from raw data domain which gets refreshed at different times T1 and T2
  • Dataset DS2 for Domain D1 depends on RD3 from raw data domain which gets refreshed at different times T3
  • Dataset DS3 for Domain D1 depends on data refresh of datasets DS1 and DS2 from Domain D1
  • Dataset DS4 for Domain D1 depends on datasets DS3 from Domain D1 and dataset DS1 from Domain D2 which is refreshed at time T4.

Solution Overview

The orchestration solution involves two main components.

1. Cross account event sharing

The following diagram illustrates the architecture for distributing data refresh events across domains within the orchestration solution using Amazon EventBridge. Data producers emit refresh events to a centralized event bus upon completing their updates. These events are then propagated to all subscribing domains. Each domain evaluates incoming events against its pipeline dependency configurations, enabling precise and prompt triggering of downstream data pipelines.

Cross Account Event Publish Using Eventbridge

The following snippet shows the data refresh event:


Sample EventBridge cross account event forward rule.

The following screenshots depicts a sample data refresh event that will be broadcasted to consumer data domains.


2. Data Pipeline orchestration

The following diagram describes the technical architecture of the orchestration solution using several AWS services such as Amazon Eventbridge, Amazon SQS, AWS Lambda, AWS Glue, Amazon SNS and Amazon Aurora.

The orchestration solution revolves around five core processors.

Data product pipeline scheduler

The scheduler is a daily scheduled Glue job that finds data products that are due for data refresh based on orchestration metadata and, for each identified data product, the scheduler retrieves both internal and external dependencies and stores them in the orchestration state management system database tables with a status of WAITING.

Data refresh events processor

Data refresh events are emitted from a central event bus and routed to domain-specific event buses. These domain buses send the events to a message queue for asynchronous processing. Any undeliverable events are redirected to a dead-letter queue for further inspection and recovery.

The event processor Lambda function consumes messages from the queue and evaluates whether the incoming event corresponds to any defined dependencies within the domain. If a match is found, the dependency status is updated from WAITING to ARRIVED. The processor also checks whether all dependencies for a given data product have been satisfied. If so, it starts the corresponding pipeline execution workflow by triggering an AWS Step Functions state machine.

Data product pipeline processor

Retrieves orchestration metadata to find the pipeline configuration and associated Glue job and parameters for the target data product. Triggers the Glue job using the retrieved configuration and parameters. This step ensures that the pipeline is launched with the correct context and input values. It also captures the Glue job run Id and updates the data product status to PROCESSING within the orchestration state management database, enabling downstream monitoring and status tracking.

Data product pipeline status processor

Each domain’s EventBridge is configured to listen for AWS Glue job state change events, which are routed to a message queue for asynchronous processing. A processing function evaluates incoming job state events:

  • For successful job completions, the corresponding pipeline status is updated from PROCESSING to COMPLETED in the orchestration state database. If the pipeline is configured to publish downstream events, a data refresh event is emitted to the central event bus.
  • For failed jobs, the pipeline status is updated from PROCESSING to ERROR, enabling downstream systems to manage exceptions or start retrying of a failed job.
  • Sample Glue Job state change events for successful completion. The glue job name from the event is used to update the status of the data product.

Data product pipeline monitor

The pipeline monitoring system operates through an EventBridge scheduled trigger that activates every 10 minutes to scan the orchestration state. During this scan, it identifies data products with satisfied dependencies but pending pipeline execution and initiates those pipelines automatically. When pipeline reruns are necessary, the system resets the orchestration state, allowing the monitor to reassess dependencies and trigger the appropriate pipelines. Any pipeline failures are promptly captured as exception notifications and directed to a dedicated notification queue for thorough analysis and team alerting.

Orchestration metadata data model

The following diagram describes the reference data model for storing the dependencies and state management of the data pipelines.

Table Name Description
data_product This table stores information on the data product and settings such publishing event for the data product.
data_product_dependencies This table stores information on the data product dependencies for both internal and external data products.
data_product_schedule This table stores information on the data product run schedule (Ex: daily / weekly)
data_pipeline_config This table stores information about the Glue job used for the data pipeline (ex: Name of the glue job, connections)
data_pipeline_parameters This table stores the Glue job parameters
data_product_status This table tracks the execution status of the data product pipeline, transitioning states from ‘Waiting’ to either ‘Complete’ or ‘Error’ based on runtime outcomes
data_product_dependencies_events_status This table stores the status of data dependencies refresh status. It is used to keep track of the dependencies and updates the status as the data refresh events arrive
data_product_status_history This table stores the historical data of data product data pipeline executions for audit and reporting
data_product_dependencies_events_status_history This table stores the historical data of data product data dependency status for audit and reporting

Outcome

With data pipeline orchestration and use of AWS serverless services, Stifel was able to speed up the data refresh process by cutting down the lag time associated with fixed scheduling of triggering data pipelines as well increase the parallelism of executing the data pipelines which was a constraint with on-premises data platform. This approach offers:

  • Scalability by supporting coordination across multiple data domains.
  • Reliability through automated tracking and resolution of pipeline dependencies.
  • Timeliness by ensuring pipelines are executed precisely when their prerequisites are met.
  • Cost optimization by leveraging AWS serverless technologies Lambda for compute, EventBridge for event routing, Aurora Serverless for database operations, and Step Functions for workflow orchestration and pay only for actual usage rather than provisioned capacity while providing automatic scaling to handle varying workloads.

Conclusion

In this post, we showed how a modular, event-driven orchestration solution can effectively manage cross-domain data pipelines. Organizations can refer to this blog post to build robust data pipeline orchestration avoiding rigid schedules and dependencies by leveraging event-based triggers.

Special thanks: This implementation success is a result of close collaboration between Stifel Financial leadership team (Kyle Broussard Managing Director, Martin Nieuwoudt Director of Data Strategy & Analytics) , AWS ProServe, and the AWS account team. We want to thank Stifel Financial Executives and the Leadership Team for the strong sponsorship and direction.

About the authors

Amit Maindola

Amit Maindola

Amit is a Senior Data Architect with AWS ProServe team focused on data engineering, analytics, and AI/ML. He helps customers in their digital transformation journey and enables them to build highly scalable, robust, and secure cloud-based analytical solutions on AWS to gain timely insights and make critical business decisions.

Srinivas Kandi

Srinivas Kandi

Srinivas is a Senior Architect at Stifel focusing on delivering the next generation of cloud data platform on AWS. Prior to joining Stifel, Srini was a delivery specialist in cloud data analytics at AWS helping several customers in their transformational journey into AWS cloud. In his free time, Srini likes to explore cooking, travel and learn new trends and innovations in AI and cloud computing.

Hossein Johari

Hossein Johari

Hossein is a seasoned data and analytics leader with over 25 years of experience architecting enterprise-scale platforms. As Lead and Senior Architect at Stifel Financial Corp. in St. Louis, Missouri, he spearheads initiatives in Data Platforms and Strategic Solutions, driving the design and implementation of innovative frameworks that support enterprise-wide analytics, strategic decision-making, and digital transformation. Known for aligning technical vision with business objectives, he works closely with cross-functional teams to deliver scalable, forward-looking solutions that advance organizational agility and performance.

Ahmad Rawashdeh

Ahmad Rawashdeh

Ahmad is a Senior Architect at Stifel Financial. He supports Stifel and its clients in designing, implementing, and building scalable and reliable data architectures on Amazon Web Services (AWS), with a strong focus on data lake strategies, database services, and efficient data ingestion and transformation pipelines.

Lei Meng

Lei Meng

Lei is a data architect at Stifel. His focus is working in designing and implementing scalable and secure data solutions on the AWS and helping Stifel’s cloud migration from on-premises systems.