Tag Archives: announcements

AWS Week in Review – April 4, 2022

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-week-in-review-april-4-2022/

This post is part of our Week in Review series. Check back each week for a quick round up of interesting news and announcements from AWS!

Welcome to the April 4 edition of the AWS Week in Review. This week, alongside the main launches, I also captured a couple of new capabilities, such as a new API to manage your AWS accounts within AWS Organizations, an easier process to update your AWS Lambda layers, and a new behavior of Amazon Elastic Compute Cloud (Amazon EC2).

Last Week’s Launches
Here are some launches that caught my attention last week:

Sustainability Pillar is now available in the Well Architect Tool – The Well Architected Tool is a central place for cloud architecture best practices and guidance. The Sustainability Pillar was announced at the re:Invent 2021 conference. It helps you to learn, measure, and improve your workloads using environmental best practices for cloud computing.

Close an AWS Member Account with an API Call – This feature was launched with little fanfare, but it is a big deal for those of you managing large numbers of AWS accounts through Organizations.  The Twitter community first spotted the change, noticing a commit in the AWS SDK for Go. See the official blog post announcement for more information!

The Lambda Console Now Allows Updates a Lambda Layer in All or a Subset of Functions – Lambda layers provide a convenient way to package libraries and other dependencies that you can use with your Lambda functions. Using layers reduces the size of uploaded deployment archives and makes it faster to deploy your code. Previously, it was challenging to identify and update all the functions that used a specific layer version. With this release, the Lambda console displays a list of all the functions using a given layer and allows you to select multiple functions to be updated with a newer layer version. It eliminates the need to update one function at a time or utilize an external script to perform the update on multiple functions.

Amazon EC2 Launched Automatic Recovery on Hardware Failure by Default – This new feature makes it easier to recover your instance when it becomes unreachable. Automatic recovery improves instance availability by recovering the instance if it becomes impaired due to an underlying hardware issue. Automatic recovery migrates the instance to another hardware during an instance reboot while retaining its instance ID, private IP addresses, Elastic IP addresses, and all instance metadata. You can choose to disable automatic recovery for your instance if you wish.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
Beside launches, here are other news worthy items and a blog that caught my attention:

New AWS podcast for Sub-Saharan AWS communities – There are AWS podcasts in many different languages: English, French, Italian, German, three in Spanish, and Russian just to name a few. This week, my colleague Veliswa launched an English podcast aimed at highlighting the Sub-Saharian AWS communities and customers. You can listen to it using any good podcast application (including but not only Spotify and Apple).

100th episode of Le Podcast AWS en Français – This week also marked the publication of the 100th episode of the AWS French Podcast. Since its start in 2019, the podcast has seen 250k downloads. Thank you for listening.

AWS Open Source News and Updates – My colleague Ricardo writes this weekly open-source newsletter. In the 106th edition, I noticed two pieces of information important for the Java community:

First, we released Amazon Corretto 18. This version supports the latest Java feature release OpenJDK 18, and is available on Linux, Windows, and macOS. OpenJDK 18 offers a new internet-address resolution capability, a Simple Web Server, an updated Vector API, a new @snippet Tag for JavaDoc, a new implementation of Core Reflection, a change to UTF-8 as the default character set (charset) of the standard Java APIs, a second iteration of the foreign memory API, advancements in pattern matching for switch statements, and the deprecation of finalization.

Second, we published a blog post showing how to reduce Lambda cold start time by deploying your Java-based Lambda function on Quarkus. Quarkus was created by Java Champion Emmanuel Bernard. It is an open-source native Java stack tailored for GraalVM and OpenJDK HotSpot, crafted from the best of breed Java libraries and standards. It is designed to have an extremely low memory footprint and fast startup time. And yes, Quarkus runs on Corretto too.

A Cloud Guru Answers a Common Question – Nearly every week, people ask me what AWS certification they should take. A Cloud Guru walks through the decision in Which AWS certification is right for me?

Upcoming AWS Events
Check your calendars and sign up for these AWS events:

The AWS Summit season has started – The Brussels Summit was last week, and the next ones are Paris, San Francisco, and London, in that order. I will be delivering the closing keynote at the Paris Summit and will be around the Formula1 GameDay area in London. Be sure to stop by and say “Hi!” if you’re around. You can sign up to receive a notification when registration opens for a Summit in your area. If you can’t attend a Summit in person this year, we will have an online Summit for EMEA in June (at European time, but all sessions will stay available on-demand until September).

.NET Enterprise Developer Day EMEA registrations are open – .NET Enterprise Developer Day EMEA 2022 is a free, one-day virtual conference providing enterprise developers with the most relevant information to swiftly and efficiently migrate and modernize their .NET applications and workloads on AWS. It will happen online on April 26, 2022.

re:Mars conference registrations are open – Mars stands for Machine learning, Automation, Robotics, and Space. You will learn from recognized thought leaders and technical experts who are building the future of AI/ML. It will happen in Las Vegas, Nevada, between June 21 and 24, 2022.

re:Inforce conference registrations are open – Security is our first priority at AWS, and it deserves its own two-day conference to reinforce your AWS security posture. You’ll hear the latest from industry-leading speakers in security, compliance, identity, and privacy. It will happen in Boston, Massachusetts, on July 26 and 27, 2022.

That’s all for this week. Come back next Monday for another Week in Review!
— seb

AWS Week in Review – March 28, 2022

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/aws/aws-week-in-review-march-28-2022/

This post is part of our Week in Review series. Check back each week for a quick round up of interesting news and announcements from AWS!

Welcome to another round up of the most significant AWS launches from the previous week. Among the most relevant news, we have improvements done in AWS Lambda, a new service for game developers, and we are back with the AWS Summits all around the world.

Last Week’s Launches
Here are some launches that got my attention during the previous week.

AWS Lambda Now Supports Up to 10 GB Ephemeral Storage – This new launch allows you to configure the temporary file system capacity (/tmp) of Lambda up to 10 GB! This is very useful for customers that are trying to use Lambda for ETL jobs, ML inference or other data-intensive workloads. Check Channy’s launch blog post to learn more about how to get started.

Amazon GameSparks – Last week we announced the launch of Amazon GameSparks in preview. Amazon GameSparks is a new serverless service that makes it easy for developers to create, test, and tune custom game features without thinking about the underlying servers or infrastructure. It comes with out-of-the-box features ideal for game backends and it is pre-integrated with the Unity game engine. Learn more in Tabitha’s blog post.

Amazon Connect Forecasting, Capacity Planning, and Scheduling – This set of ML-powered capabilities makes it easier for contact center managers to predict customer service workloads, determine ideal staffing levels, and schedule agents accordingly. These features are available in preview and you can learn more in Sajith’s blog post.

AWS Proton Support for Terraform Open Source – Last November we announced the preview for this feature, and now it is generally available in all the AWS Regions where Proton is available. Platform teams can now define Proton templates using Terraform modules. Read the What’s New post for more information.

Amazon Polly Now Offers Neural TTS Voices in Catalan and Mexican Spanish – Polly is a service that turns your text into lifelike speech. It has support for Neural TTS voices in many languages, and last week they added two more, in Mexican Spanish and in Catalan. You can read more in the What’s New post and listen to the Mexican voice in this audio.


For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News

Podcast Charlas Técnicas de AWS – If you understand Spanish, this podcast is for you. Podcast Charlas Técnicas is one of the official AWS podcasts in Spanish. It has episodes every other week. The podcast is meant for builders, and it shares stories on how customers implemented and learned AWS and how to architect applications using AWS services. You can listen to all the episodes directly from your favorite podcast app or the podcast web page.

AWS Open Source News and Updates – Ricardo Sueiras, my colleague from the AWS Developer Relation team, runs this newsletter. It brings you all the latest open-source projects, posts and more. This week he shares the latest open source project, tools and also AWS and community blog posts related to open-source. Read edition #106 here.

Upcoming AWS Events
Check your calendars and sign up for these AWS events:

Building a Tech-Enabled Biotech with Celsius Therapeutics on Tuesday March 29 at 10 PM UTC – My colleague Mark Birch hosts regular Clubhouse events, in which he talks with different startups. These companies share their journey and experience using AWS. Join the live event here.

The AWS Summits Are Back – Don’t forget to register for the AWS Summits in Brussels (on March 31), Paris (on April 12), San Francisco (on April 20-21), and London (on April 27). More summits are coming in the next weeks, and we’ll let you know in these weekly posts.

That’s all for this week. Check back next Monday for another Week in Review!

— Marcia

Using larger ephemeral storage for AWS Lambda

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/using-larger-ephemeral-storage-for-aws-lambda/

AWS Lambda functions have always had ephemeral storage available at /tmp in the file system. This was set at 512 MB for every function, regardless of runtime or memory configuration. With this new feature, you can now configure ephemeral storage for up to 10 GB per function instance.

You can set this in the AWS Management Console, AWS CLI, or AWS SDK, AWS Serverless Application Model (AWS SAM), AWS Cloud Development Kit (AWS CDK), AWS Lambda API, and AWS CloudFormation. This blog post explains how this works and how to use this new setting in your Lambda functions.

How ephemeral storage works in Lambda

All functions have ephemeral storage available at the fixed file system location /tmp. This provides a fast file system-based scratch area that is scoped to a specific instance of a Lambda function. This storage is not shared between instances of Lambda functions and the space is guaranteed to be empty when a new instance starts.

This means that you can use the same execution environment to cache static assets in /tmp between invocations. This is a common use case that can help reduce function duration for subsequent invocations. The contents are deleted when the Lambda service eventually terminates the execution environment.

With this new configurable setting, ephemeral storage works in the same way. The behavior is identical whether you use zip or container images to deploy your functions. It’s also available for Provisioned Concurrency. All data stored in /tmp is encrypted at rest with a key managed by AWS.

Common use cases for ephemeral storage

There are three common customer use cases that can benefit from the expanded ephemeral storage.

Extract-transform-load (ETL) jobs: Your code may perform intermediate computation or download other resources to complete processing. More temporary space enables more complex ETL jobs to run in Lambda functions.

Machine learning (ML) inference: Many inference tasks rely on large reference data files, including libraries and models. More ephemeral storage allows you to download larger models from Amazon S3 to /tmp and use these in your processing. To learn more about using Lambda for ML inference, read Building deep learning inference with AWS Lambda and Amazon EFS and Pay as you go machine learning inference with AWS Lambda.

Data processing: For workloads that download objects from S3 in response to S3 events, the larger /tmp space makes it possible to handle larger objects without using in-memory processing. Workloads that create PDFs, use headless Chromium, or process media also benefit from more ephemeral storage.

Zip processing: Some workloads use large zip files from data providers to initialize local databases. These can now unzip to the local file system without the need for in-memory processing. Similarly, applications that generate zip files also benefit from more /tmp space.

Graphics processing: Image processing is a common use-case for Lambda-based applications. For workloads processing large tiff files or satellite images, this makes it easier to use libraries like ImageMagick to perform all the computation in Lambda. Customers using geospatial libraries also gain significant flexibility from writing large satellite images to /tmp.

Deploying the example application

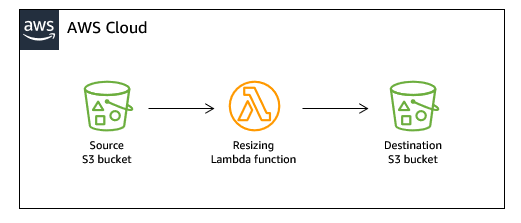
The example application shows how to resize an MP4 file from Amazon S3, using the temporary space for intermediate processing. In this example, you can process video files much larger than the standard 512 MB temporary storage:

Example application architecture

Before deploying the example, you need:

This example uses the AWS Serverless Application Model (AWS SAM). To deploy:

  1. From a terminal window, clone the GitHub repo:
    git clone https://github.com/aws-samples/s3-to-lambda-patterns
  2. Change directory to this example:
    cd ./resize-video
  3. Follow the installation instructions in the README file.

To test the application, upload an MP4 file into the source S3 bucket. After processing, the destination bucket contains the resized video file.

How the example works

The resize function downloads the original video from S3 and saves the result in Lambda’s temporary storage directory:

	// Get signed URL for source object
	const Key = decodeURIComponent(record.s3.object.key.replace(/\+/g, ' '))

	const data = await s3.getObject({
		Bucket: record.s3.bucket.name,
		Key
	}).promise()

	// Save original to tmp directory
	const tempFile = `${ffTmp}/${Key}`
	console.log('Saving downloaded file to ', tempFile)
	fs.writeFileSync(tempFile, data.Body)

The application uses FFmpeg to resize the video and store the output in the temporary storage space:

// Save resized video to /tmp
	const outputFilename = `${Key.split('.')[0]}-smaller.mp4`
	console.log(`Resizing and saving to ${outputFilename}`)
	await execPromise(`${ffmpegPath} -i "${tempFile}" -loglevel error -vf scale=160:-1 -sws_flags fast_bilinear ${ffTmp}/${outputFilename}`)

After processing, the function reads the file from the temporary directory and then uploads to the destination bucket in S3:

	const tmpData = fs.readFileSync(`${ffTmp}/${outputFilename}`)
	console.log(`tmpData size: ${tmpData.length}`)

	// Upload to S3
	console.log(`Uploading ${outputFilename} to ${outputFilename}`)
	await s3.putObject({
		Bucket: process.env.OutputBucketName,
		Key: outputFilename,
		Body: tmpData
	}).promise()
	console.log(`Object written to ${process.env.OutputBucketName}`)

Since temporary storage is not deleted between warm Lambda invocations, you may also choose to remove unneeded files. This example uses a tmpCleanup function to delete the contents of /tmp:

const fs = require('fs')
const path = require('path')
const directory = '/tmp/'

// Deletes all files in a directory
const tmpCleanup = async () => {
	console.log('Starting tmpCleanup')
	fs.readdir(directory, (err, files) => {
		return new Promise((resolve, reject) => {
			if (err) reject(err)

			console.log('Deleting: ', files)				
			for (const file of files) {
				const fullPath = path.join(directory, file)
				fs.unlink(fullPath, err => {
					if (err) reject (err)
				})
			}
			resolve()
		})
	})
}

Setting ephemeral storage with the AWS Management Console or AWS CLI

In the Lambda console, you can view the ephemeral storage allocated to a function in the Generation configuration menu in the Configuration tab:

Lambda function configuration

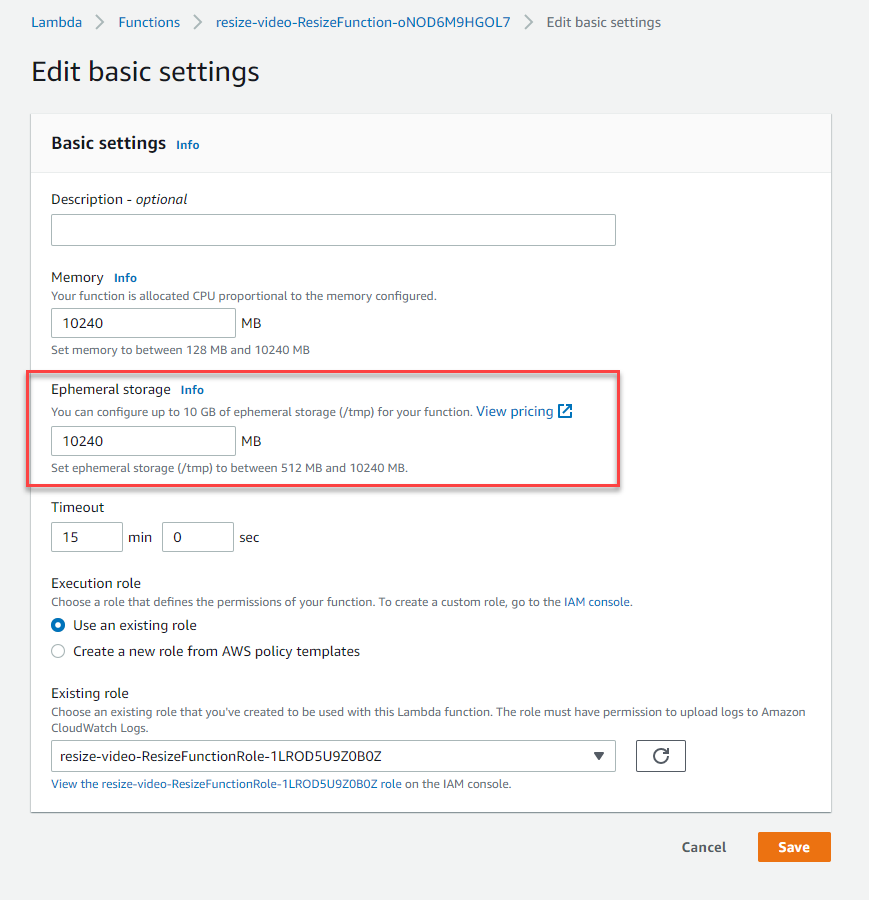
To make changes to this setting, choose Edit. In the Edit basic settings page, adjust the Ephemeral Storage to any value between 512 MB and 10240 MB. Choose Save to update the function’s settings.

Basic settings

You can also define the ephemeral storage setting in the create-function and update-function-configuration CLI commands. In both cases, use the ephemeral-storage switch to set the value:

aws lambda create-function --function-name testFunction --runtime python3.9 --handler lambda_function.lambda_handler --code S3Bucket=myBucket,S3Key=function.zip --role arn:aws:iam::123456789012:role/testFunctionRole --ephemeral-storage '{"Size": 10240}' 

To modify this setting for testFunction, run:

aws lambda update-function-configuration --function-name testFunction --ephemeral-storage '{"Size": 5000}'

Setting ephemeral storage with AWS CloudFormation or AWS SAM

You can define the size of ephemeral storage in both AWS CloudFormation and AWS SAM templates by using the EphemeralStorage attribute. As shown in the example’s template.yaml, there is a new attribute called EphemeralStorage:

  ResizeFunction:
    Type: AWS::Serverless::Function
    Properties:
      CodeUri: resizeFunction/
      Handler: app.handler
      Runtime: nodejs14.x
      Timeout: 900
      MemorySize: 10240
      EphemeralStorage:
        Size: 10240

You define this on a per-function basis. If the attribute is missing, the function is allocated 512 MB of temporary storage.

Using Lambda Insights to monitor temporary storage usage

You can use Lambda Insights to query on the metrics emitted by the Lambda function relating to the usage of temporary storage. First, enable Lambda Insights on a function by following these steps in the documentation.

After running the function, the Lambda service writes ephemeral storage metrics to Amazon CloudWatch Logs. With Lambda Insights enabled, you can now query these from the CloudWatch console. From the Logs Insights feature, you can query to determine the maximum, used, and available space available:

fields @timestamp,
tmp_max/(1024*1024),
tmp_used/(1024*1024),
tmp_free/(1024*1024)

Calculating the cost of more temporary storage

Ephemeral storage is free up to 512 MB, as it always has been. You are charged for the amount you select between 512 MB and 10,240 MB. For example, if you select 1,024 MB, you only pay for 512 MB. Expanded ephemeral storage costs $0.0000000308 per GB/second in the us-east-1 Region (see the pricing page for other Regions).

In us-east-1, for a workload invoking a Lambda function 500,000 times with a 10 second duration, using the maximum temporary storage, the cost is $0.63:

Invocations 500,000
Duration (ms) 10,000
Ephemeral storage (over 512 MB) 9,728
Storage price per GB/s $0.0000000308
GB/s total 20,480,000
Price of storage $0.63

Choosing between ephemeral storage and Amazon EFS

Generally, ephemeral storage is designed for intermediary processing of a function. You can download reference data, machine learning models, or database metadata from other sources such as Amazon S3, and store these in /tmp for further processing. Ephemeral storage can provide a cache for data for repeat usage across invocations and offers fast I/O throughout.

Alternatively, EFS is primarily intended for customers that need to:

  • Share data or state across function invocations.
  • Process files larger than the 10,240 MB storage allows.
  • Use file-system type functionality, such as appending to or modifying files.

Conclusion

Serverless developers can now configure the amount of temporary storage available in AWS Lambda functions. This blog post discusses common use cases and walks through an example application that uses larger temporary storage. It also shows how to configure this in CloudFormation and AWS SAM and explains the cost if you use more than the free, provisioned 512 MB that’s automatically provisioned for every function.

For more serverless learning resources, visit Serverless Land.

Migration updates announced at re:Invent 2021

Post Syndicated from Angélica Ortega original https://aws.amazon.com/blogs/architecture/migration-updates-announced-at-reinvent-2021/

re:Invent is a yearly event that offers learning and networking opportunities for the global cloud computing community. 2021 marks the launch of several new features in different areas of cloud services and migration.

In this blog, we’ll cover some of the most important recent announcements.

AWS Mainframe Modernization (Preview)

Mainframe modernization has become a necessity for many companies. One of the main drivers fueling this requirement is the need for agility, as the market constantly demands new functionalities. The mainframe platform, due to its complex dependencies, long procurement cycles, and escalating costs, makes it impossible for companies to innovate at the needed pace.

Mainframe modernization can be a complex undertaking. To assist you, we have launched a comprehensive platform, called AWS Mainframe Modernization, that enables two popular migration patterns: replatforming, and automated refactoring.

AWS Mainframe Modernization flow

Figure 1. AWS Mainframe Modernization flow

AWS Migration and Modernization Competency

Application modernization is becoming an important migration strategy, especially for strategic business applications. It brings many benefits: software licensing and operation cost optimization, better performance, agility, resilience, and more. Selecting a partner with the required expertise can help reduce the time and risk for these kinds of projects. In the next section, you’ll find a summary of the experience required by a partner to get the AWS Migration and Modernization Competency. More information can be found at AWS Migration Competency Partners.

AWS Application Migration Service (AWS MGN)

AWS MGN is recommended as the primary migration service for lift and shift migrations. Customers currently using AWS Server Migration Service are encouraged to switch to it for future migrations.

Starting in November 2021, AWS MGN supports agentless replication from VMWare vCenter versions 6.7 and 7.0 to the AWS Cloud. This new feature is intended for users who want to rehost their applications to AWS, but cannot install the AWS Replication Agent on individual servers due to company policies or technical restrictions.

AWS Elastic Disaster Recovery

Two of the pillars of the Well-Architected Framework are Operational Excellence and Reliability. Both are directly concerned with the capability of a service to recover and work efficiently. AWS Elastic Disaster Recovery is a new service to help you to minimize downtime and data loss with fast, reliable, and recovery of on-premises and cloud-based applications. It uses storage, compute, point-in-time recovery, and cost-optimization.

AWS Resilience Hub

AWS Resilience Hub is a service designed to help customers define, measure, and manage the resilience of their applications in the cloud. This service helps you define RTO (Recovery Time Objective) and RPO (Recovery Point Objective) and evaluates the configuration to meet the requirements defined. Aligned with the AWS Well-Architected Framework, this service can recover applications deployed with AWS CloudFormation, and integrates with AWS Fault Injection Simulator, AWS Systems Manager, or Amazon CloudWatch.

AWS Migration Hub Strategy Recommendations

One of the critical tasks in a migration is determining the right strategy. AWS Migration Hub can help you build a migration and modernization strategy for applications running on-premises or in AWS. AWS Migration Hub Strategy Recommendations were announced on October 2021. It’s designed to be the starting point for your cloud journey. It helps you to assess the appropriate strategy to transform your portfolios to use the full benefits of cloud services.

AWS Migration Hub Refactor Spaces (Preview)

Refactoring is the migration strategy that requires the biggest effort, but it permits you to take full advantage of cloud-native features to improve agility, performance, and scalability. AWS Migration Hub Refactor Spaces is the starting point for incremental application refactoring to microservices in AWS. It will help you reduce the undifferentiated heavy lifting of building and operating your AWS infrastructure for incremental refactoring.

AWS Database Migration Service

AWS Database Migration Service (AWS DMS) is a service that helps you migrate databases to AWS quickly and securely.

AWS DMS Fleet Advisor is a new free feature of AWS DMS that enables you to quickly build a database and analytics migration plan, by automating the discovery and analysis of your fleet. AWS DMS Fleet Advisor is intended for users looking to migrate a large number of database and analytic servers to AWS.

AWS Microservice Extractor for .NET is a new free tool and simplifies the process of re-architecting applications into smaller code projects. Modernize and transform your .NET applications with an assistive tool that analyzes source code and runtime metrics. It creates a visual representation of your application and its dependencies.

This tool visualizes your applications source code, helps with code refactoring, and assists in extraction of the code base into separate code projects.  Teams can then develop, build, and operate independently to improve agility, uptime, and scalability.

AWS Migration Evaluator

AWS Migration Evaluator (ME) is a migration assessment service that helps you create a directional business case for AWS Cloud planning and migration. Building a business case for the cloud can be a time-consuming process on your own. With Migration Evaluator, organizations can accelerate their evaluation and decision-making for migration to AWS. During 2021, there were some existing improvements to mention:

  • Quick Insights. This new capability of Migration Evaluator, provides customers with a one-page summary of their projected AWS costs, based on measured on-premises provisioning and utilization.
  • Enhanced Microsoft SQL Discovery. This is a new feature of the Migration Evaluator Collector, which assists you by including your SQL Server environment in their migration assessment.
  • Agentless Collection for Dependency Mapping. The ME Collector now enables agentless network traffic collection to be sent to the customer’s AWS Migration Hub account.

AWS Amplify Studio

This is a visual development environment that offers frontend developers new features to accelerate UI development with minimal coding, while integrating with Amplify. Read Introducing AWS Amplify Studio.

Conclusion

Migration is a crucial process for many enterprises as they move from on-premises systems to the cloud. It helps accelerate your cloud journey, and offers additional tools and methodologies created by AWS. AWS has created and is continually improving services and features to optimize the migration process and help you reach your business goals faster.

Related information

ISO/IEC 27001 certificates now available in French and Spanish

Post Syndicated from Rodrigo Fiuza original https://aws.amazon.com/blogs/security/iso-iec-27001-certificates-now-available-in-french-and-spanish/

French version
Spanish version

We continue to listen to our customers, regulators, and stakeholders to understand their needs regarding audit, assurance, certification, and attestation programs at Amazon Web Services (AWS). We are pleased to announce that ISO/IEC 27001 certificates for AWS are now available in French and Spanish on AWS Artifact. These translated reports will help drive greater engagement and alignment with customer and regulatory requirements across Latin America, Canada, and EMEA.

Current translated (French and Spanish) ISO/IEC 27001 certificates are available through AWS Artifact. Future ISO certificates will be published on an annual basis in accordance with the audit period.

We value your feedback and questions—feel free to reach out to our team or give feedback about this post through our Contact Us page.

If you have feedback about this post, submit comments in the Comments section below.

Want more AWS Security news? Follow us on Twitter.

.


Les certificats ISO/IEC 27001 sont désormais disponibles en français et en espagnol

Nous restons à l’écoute de nos clients, des régulateurs et des parties prenantes pour comprendre leurs besoins en matière de programmes d’audit, d’assurance, de certification et d’attestation chez Amazon Web Services (AWS). Nous avons le plaisir d’annoncer que les certificats ISO/IEC 27001 d’AWS sont désormais disponibles en français et en espagnol sur AWS Artifact. Ces rapports traduits permettront de renforcer l’engagement et l’alignement sur les exigences des clients et des réglementations en Amérique latine, au Canada et en EMEA.

Les certificats ISO/IEC 27001 actuellement traduits (français et espagnol) sont disponibles via AWS Artifact. Les futurs certificats ISO seront publiés sur une base annuelle en fonction de la période d’audit.

Vos commentaires et vos questions sont importants pour nous. N’hésitez pas à contacter notre équipe ou à nous faire part de vos commentaires sur cet article par le biais de notre page Nous contacter.

Si vous avez des commentaires sur cet article, envoyez-les dans la section Commentaires ci-dessous.

Vous voulez plus d’informations sur la sécurité AWS ? Suivez-nous sur Twitter.

.


Los certificados ISO/IEC 27001 ahora están disponibles en francés y español

Seguimos escuchando a nuestros clientes y reguladores y entendemos sus necesidades con respecto a los programas de garantías en Amazon Web Services (AWS) y nos complace anunciar que los certificados ISO/IEC 27001 ya están disponibles en francés y español. Estos certificados traducidos ayudarán a impulsar los requisitos regulatorios y de los clientes locales en las regiones de LATAM, Canadá y EMEA.

Los certificados ISO/IEC 27001 traducidos actualmente (Francés y Español) están disponibles en AWS Artifact. Los futuros certificados ISO se publicarán anualmente según el período de auditoría.

Valoramos sus comentarios y preguntas; no dude en ponerse en contacto con nuestro equipo o enviarnos sus comentarios sobre esta publicación a través de nuestra página Contáctenos.

Si tienes comentarios sobre esta publicación, envía comentarios en la sección Comentarios a continuación.

¿Desea obtener más noticias sobre seguridad de AWS? Síguenos en Twitter.

Author

Rodrigo Fiuza

Rodrigo is a security audit manager at AWS, based in São Paulo. He leads audits, attestations, certifications, and assessments across Latin America, the Caribbean, and Europe. Rodrigo previously worked in risk management, security assurance, and technology audits for 12 years.

Naranjan Goklani

Naranjan Goklani

Naranjan is a security audit manager at AWS, based in Toronto. He leads audits, attestations, certifications, and assessments across North America and Europe. Naranjan has previously worked in risk management, security assurance, and technology audits for the past 12 years.

Author

Sonali Vaidya

Sonali is a compliance program manager at AWS, where she leads multiple global compliance programs including HITRUST, ISO 27001, ISO 27017, ISO 27018, ISO 27701, ISO 9001, ISO 22301, and CSA STAR. Sonali has over 20 years of experience in information security and privacy management and holds multiple certifications such as CISSP, CCSK, CEH, CISA, and ISO 22301 LA.

AWS Week in Review – March 21, 2022

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/aws-week-in-review-march-21-2022/

This post is part of our Week in Review series. Check back each week for a quick round up of interesting news and announcements from AWS!

Another week, another round up of the most significant AWS launches from the previous seven days! Among the news, we have new AWS Heroes and a cost reduction. Also, improvements for customers using AWS Lambda and Amazon Elastic Kubernetes Service (EKS), and a new database-to-database connectivity option for Amazon Relational Database Service (RDS).

Last Week’s Launches
Here are some launches that caught my attention last week:

AWS Billing Conductor – This new tool provides customizable pricing and cost visibility for your end customers or business units and helps when you have specific showback and chargeback needs. To get started, see Getting Started with AWS Billing Conductor. And yes, you can call it “ABC.”

Cost Reduction for Amazon Route 53 Resolver DNS Firewall – Starting from the beginning of March, we are introducing a new tiered pricing structure that reduces query processing fees as your query volume increases. We are also implementing internal optimizations to reduce the number of DNS queries for which you are charged without affecting the number of DNS queries that are inspected or introducing any other changes to your security posture. For more info, see the What’s New.

Share Test Events in the Lambda Console With Other Developers – You can now share the test events you create in the Lambda console with other team members and have a consistent set of test events across your team. This new capability is based on Amazon EventBridge schemas and is available in the AWS Regions where both Lambda and EventBridge are available. Have a look at the What’s New for more details.

Use containerd with Windows Worker Nodes Managed by Amazon EKS – containerd is a container runtime that manages the complete container lifecycle on its host system with an emphasis on simplicity, robustness, and portability. In this way, you can get on Windows similar performance, security, and stability benefits to those available for Linux worker nodes. Here’s the What’s New with more info.

Amazon RDS for PostgreSQL databases can now connect and retrieve data from MySQL databases – You can connect your RDS PostgreSQL databases to Amazon Aurora MySQL-compatible, MySQL, and MariaDB databases. This capability works by adding support to mysql_fdw, an extension that implements a Foreign Data Wrapper (FDW) for MySQL. Foreign Data Wrappers are libraries that PostgreSQL databases can use to communicate with an external data source. Find more info in the What’s New.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
New AWS Heroes – It’s great to see both new and familiar faces joining the AWS Heroes program, a worldwide initiative that acknowledges individuals who have truly gone above and beyond to share knowledge in technical communities. Get to know them in the blog post!

More Than 400 Points of Presence for Amazon CloudFront – Impressive growth here, doubling the Points of Presence we had in October 2019. This number includes edge locations and mid-tier caches in AWS Regions. Do you know that edge locations are connected to the AWS Regions through the AWS network backbone? It’s a fully redundant, multiple 100GbE parallel fiber that circles the globe and links with tens of thousands of networks for improved origin fetches and dynamic content acceleration.

AWS Open Source News and Updates – A newsletter curated by my colleague Ricardo where he brings you the latest open-source projects, posts, events, and much more. This week he is also sharing a short list of some of the open-source roles currently open across Amazon and AWS, covering a broad range of open-source technologies. Read edition #105 here.

Upcoming AWS Events
Check your calendars and sign up for these AWS events:

The AWS Summits Are Back – Don’t forget to register to the AWS Summits in Brussels (on March 31) and Paris (on April 12). More summits are coming in the next weeks, and we’ll let you know in this weekly posts.

That’s all from me for this week. Come back next Monday for another Week in Review!
— Danilo

Get to know the first AWS Heroes of 2022!

Post Syndicated from Ross Barich original https://aws.amazon.com/blogs/aws/get-to-know-the-first-aws-heroes-of-2022/

The AWS Heroes program is a worldwide initiative which acknowledges individuals who have truly gone above and beyond to share knowledge in technical communities. AWS Heroes share knowledge by hosting events, Meetups, workshops, and study groups, or by authoring blogs, creating videos, speaking at conferences, or contributing to open source projects. You can see some of the Heroes’ work in the AWS Heroes Content Library.

Today we are excited to introduce the first new Heroes of 2022, including the first Hero based in the Czech Republic:

Albert Suwandhi – Medan, Indonesia

Community Hero Albert Suwandhi is an academic and IT Professional, and an AWS Champion Authorized Instructor who delivers AWS classroom training courses to AWS users and customers. He strongly believes in the power of community: he joined AWS User Group Indonesia, Medan chapter in 2019 and has since organized and delivered several sharing sessions. He has also been featured in number of tech talks, and his areas of cloud computing interest are cloud architecture and security. He enjoys helping people to realize the true potential of cloud computing and he runs a YouTube channel, which provides tutorials and tips & tricks related to AWS.

Dipali Kulshrestha – Delhi, India

Community Hero Dipali Kulshrestha is Vice President of Data Engineering at Natwest Group where she is an AWS trainer & mentor, conducting Cloud Practitioner and Solution Architect workshops every quarter. She is also an AWS Delhi User Group leader, hosts monthly immersive learning sessions on different AWS concepts, and is an active speaker at AWS community events. Dipali released a DevOps with AWS course on LinkedIn Learning, attended by 12000+ learners. She also created an AWS re:Skill series for containers on AWS. Dipali is huge advocate of diversity & inclusion of women in tech, and was recently featured in AWS India’s campaign called Developers of AWS and in a Tech Gig interview about cloud upskilling.

Faizal Khan – Hyderabad, India

Community Hero Faizal Khan is a tech entrepreneur, currently Founder & CEO at Ecomm.in and Xite Logic. He is an ardent contributor to the AWS community. As organizer of the AWS Hyderabad User Group, he helps organize AWS hackathons, AWS Meetups, re:Invent recaps, webinars, and AWS certification bootcamps. He is also a speaker at many events covering Networking, IoT, Storage, and Compute. His VPC masterclass on YouTube has garnered about half a million views. He was a core organizing member and host for the AWS Community Day South Asia 2021 Online, which attracted over 24K viewers. In addition, he built an AWS Q&A discussion forum for the community.

Filip Pyrek – Brno, Czech Republic

Serverless Hero Filip Pyrek is Serverless Architect at Purple Technology. At the age of 23 Filip is one of the youngest AWS Heroes. He started his serverless journey back in 2016 when he was 17 years old. He is helping grow the serverless community in Czech Republic and Slovakia by organizing Serverless Brno meetups, contributing to local podcasts, writing serverless blog posts in Czech language, and doing other evangelization activities. He is in touch with a community of maintainers and developers of serverless tooling projects and provides them with feedback, feature requests, and open-source contributions in order to continuously improve the serverless ecosystem.

Karolina Boboli – Warsaw, Poland

Community Hero Karolina Boboli works as an AWS Cloud Architect and Consultant. She has experience in cloud security, cloud governance, cost management, landing zones, serverless, and IoT. She created an online course “AWS in practice – your first project” about infrastructure as code. In 2019 she founded a vibrant cloud community – swiatchmury.pl – a Slack for cloud professionals focused on AWS – which she runs on a daily basis. The goal of the community is to have a friendly place to ask questions, inspire each other, and simply be together. From time to time she gives talks in AWS UG Poland and organizes her own webinars.

Masaya Arai – Kanagawa, Japan

Container Hero Masaya Arai is an 11x certified Tech Lead working for Nomura Research Institute (NRI). He is the central organizer of the JAWS-UG Container chapter (about 3000 registered members), an AWS user group in Japan, and he regularly contributes to activities in the AWS user community. Masaya wrote a commercial magazine called “AWS Container Guide + Hands-on”, which became a best-selling cloud-related book on amazon.co.jp, and published more than 10,000 copies. He focuses on promoting development of AWS container technologies through a wide variety of activities such as blogs, public presentations, contributing to magazines, and writing books. He truly enjoys sharing his knowledge and experience with others.

Mayank Pandey – Bengaluru, India

Community Hero Mayank Pandey is a cloud architect & teacher, helping both small and large organizations in their cloud adoption journey. He holds Professional & Specialty AWS Certifications and handles assignments including security & cost optimization on AWS, and cloud-native applications. Mayank is passionate about teaching and has done several classroom and online trainings. He is an active member of AWS community and contributes with hands-on demos and video tutorials to the YouTube channel – KnowledgeIndia. The YouTube channel has 65,000 subscribers and 150+ videos on various AWS topics.

Niv Yungelson – Tel Aviv, Israel

Community Hero Niv Yungelson works at Melio as the DevOps Team Lead. She is co-leader of the AWS Israel User Group, one of the biggest AWS User Groups in the world. As a community leader, she organizes Meetups and ensures they include underrepresented groups in the technology industry. She achieves this by both collaborating with other User Groups and experimenting with new initiatives. Niv also volunteers as an instructor in OpsSchool, which is a non-profit program meant to gather industry leaders to contribute together, train new DevOps engineers, and help the community continue the cycle of good deeds. She is active in tech user groups, forums, and Meetups, and is committed to sharing her knowledge and experience at any given opportunity.


If you’d like to learn more about the new Heroes, or connect with a Hero near you, please visit the AWS Heroes website or browse the AWS Heroes Content Library.

— Ross;

New – Amazon EC2 X2idn and X2iedn Instances for Memory-Intensive Workloads with Higher Network Bandwidth

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/new-amazon-ec2-x2idn-and-x2iedn-instances-for-memory-intensive-workloads-with-higher-network-bandwidth/

In 2016, we launched Amazon EC2 X1 instances designed for large-scale and in-memory applications in the cloud. The price per GiB of RAM for X1 instances is among the lowest. X1 instances are ideal for high performance computing (HPC) applications and running in-memory databases like SAP HANA and big data processing engines such as Apache Spark or Presto.

The following year, we launched X1e instances with up to 4 TiB of memory designed to run SAP HANA and other memory-intensive, in-memory applications. These instances are certified by SAP to run production environments of the next-generation Business Suite S/4HANA, Business Suite on HANA (SoH), Business Warehouse on HANA (BW), and Data Mart Solutions on HANA on the AWS Cloud.

Today, I am happy to announce the general availability of Amazon EC2 X2idn/X2iedn instances, built on the AWS Nitro system and featuring the third-generation Intel Xeon Scalable (Ice Lake) processors with up to 50 percent higher compute price performance than comparable X1 instances. These improvements result in up to 45 percent higher SAP Application Performance Standard (SAPS) performance than comparable X1 instances.

You might have noticed that we’re now using the “i” suffix in the instance type to specify that the instances are using an Intel processor, “e” in the memory-optimized instance family to indicate extended memory, “d” with local NVMe-based SSDs that are physically connected to the host server, and “n” to support higher network bandwidth up to 100 Gbps.

X2idn instances enable up to 2 TiB of memory, while X2iedn instances enable up to 4 TiB of memory. X2idn and X2iedn instances also support 100 Gbps of network performance with hardware-enabled VPC encryption and support 80 Gbps of Amazon EBS bandwidth and 260k IOPs with EBS-encrypted volumes.

Instance Name vCPUs RAM (GiB) Local NVMe SSD Storage (GB) Network Bandwidth (Gbps) EBS-Optimized Bandwidth (Gbps)
x2idn.16xlarge 64 1024 1 x 1900 Up to 50 Up to 40
x2idn.24xlarge 96 1536 1 x 1425 75 60
x2idn.32xlarge 128 2048 2 x 1900 100 80
x2iedn.xlarge 4 128 1 x 118 Up to 25 Up to 20
x2iedn.2xlarge 8 256 1 x 237 Up to 25 Up to 20
x2iedn.4xlarge 16 512 1 x 475 Up to 25 Up to 20
x2iedn.8xlarge 32 1024 1 x 950 25 20
x2iedn.16xlarge 64 2048 1 x 1900 50 40
x2iedn.24xlarge 96 3072 2 x 1425 75 60
x2iedn.32xlarge 128 4096 2 x 1900 100 80

X2idn instances are ideal for running large in-memory databases such as SAP HANA. All of the X2idn instance sizes are certified by SAP for production HANA and S/4HANA workloads. In addition, X2idn instances are ideal for memory-intensive and latency-sensitive workloads such as Apache Spark and Presto, and for generating real-time analytics, processing giant graphs using Neo4j or Titan, or creating enormous caches.

X2iedn instances are optimized for applications that seek high memory to vCPU ratio and deliver the highest memory capacity per vCPU among all virtualized EC2 instance types. X2iedn is suited to run high-performance databases (such as Oracle DB, SQL server) and in-memory workloads (such as SAP HANA, Redis). Workloads that are sensitized to per-core licensing, such as Oracle DB, greatly benefit from the higher memory per vCPU (32GB:1vCPU) offered by X2iedn. X2iedn allows you to optimize licensing costs because it provides customers the same memory at half the number of vCPU compared to X2idn.

These instances offer the same amount of local storage as in X1/X1e, up to 3.8 TB, but the local storage in X2idn/X2iedn is NVMe-based, which will offer an order of magnitude lower latency compared to SATA SSDs in X1/X1e.

Things to Know
Here are some fun facts about the X2idn and X2iedn instances:

Optimizing CPU—You can disable Intel Hyper-Threading Technology for workloads that perform well with single-threaded CPUs, like some HPC applications.

NUMA—You can make use of non-uniform memory access (NUMA) on X2idn and X2iedn instances. This advanced feature is worth exploring if you have a deep understanding of your application’s memory access patterns.

Available Now
X2idn instances are now available in the US East (N. Virginia), Asia Pacific (Mumbai, Singapore, Tokyo), Europe (Frankfurt, Ireland) Regions.

X2iedn instances are now available in the US East (Ohio, N. Virginia), US West (Oregon), Asia Pacific (Singapore, Tokyo), Europe (Frankfurt, Ireland) Regions.

You can use On-Demand Instances, Reserved Instances, Savings Plan, and Spot Instances. Dedicated Instances and Dedicated Hosts are also available.

To learn more, visit our EC2 X2i Instances page, and please send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

– Channy

Customers can now request the AWS CyberGRX report for their third-party supplier due diligence

Post Syndicated from Niyaz Noor original https://aws.amazon.com/blogs/security/customers-can-now-request-the-aws-cybergrx-report-for-their-third-party-supplier-due-diligence/

CyberGRX

Gaining and maintaining customer trust is an ongoing commitment at Amazon Web Services (AWS). We are continuously expanding our compliance programs to provide customers with more tools and resources to be able to perform effective due diligence on AWS. We are excited to announce the availability of the AWS CyberGRX report for our customers.

With the increase in adoption of cloud platforms and services across multiple sectors and industries, AWS has become one of the most critical components of customers’ third-party ecosystems. Regulated customers, such as those in the financial services sector, are held to higher standards by their regulators and auditors when it comes to exercising effective due diligence on their third parties. Customers are using third-party cyber risk management (TPCRM) platforms such as CyberGRX to better manage risks from their evolving third-party ecosystems and drive operational efficiencies. To help customers in such efforts, AWS has completed CyberGRX assessment of its security posture. The assessment is performed annually and is validated by independent CyberGRX partners.

CyberGRX assessment applies a dynamic approach to third-party risk assessment, which is updated in line with changes in risk level of cloud service providers, or as AWS updates its security posture and controls. This approach eliminates outdated static spreadsheets for third-party risk assessments, in which the risk matrices are not updated in near real time. CyberGRX assessment provides advanced capabilities by integrating AWS responses with analytics, threat intelligence, and sophisticated risk models to provide an in-depth view of the AWS security posture. In addition, AWS customers can use CyberGRX’s Framework Mapper feature to map AWS assessment controls and responses to well-known industry standards and frameworks (such as NIST 800-53, NIST Cybersecurity Framework (CSF), ISO 27001, PCI DSS, HIPAA) which can significantly reduce customers’ third-party supplier due-diligence burden.

The AWS CyberGRX report is available to all customers free of cost. Customers can request access to the report by completing an access request form, available on the AWS CyberGRX page.

As always, we value your feedback and questions. Reach out to the AWS Compliance team through the Contact Us page, or if you have feedback about this post, submit comments in the Comments section below. To learn more about our other compliance and security programs, see AWS Compliance Programs.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Author

Niyaz Noor

Niyaz is the Security Audit Program Manager at AWS. Niyaz leads multiple security certification programs across Europe and other regions. During his professional career, he has helped multiple cloud service providers in obtaining global and regional security certification. He is passionate about delivering programs that build customers’ trust and provide them assurance on cloud security.

Naranjan Goklani

Naranjan Goklani

Naranjan is a Security Audit Manager at AWS, based in Toronto. He leads audits, attestations, certifications, and assessments across North America and Europe. Naranjan has previously worked in risk management, security assurance, and technology audits for the past 12 years.

Celebrate International Women’s Day all week with the Architecture Blog

Post Syndicated from Bonnie McClure original https://aws.amazon.com/blogs/architecture/celebrate-international-womens-day-with-us-on-the-architecture-blog/

Companies committed to diversity (gender or otherwise) tend to be more creative and innovative and have higher retention and engagement rates. Diverse leadership can provide excellent role models for younger people looking for a career in STEM, those who are transitioning into the industry from an “unconventional” career path, or those who are returning to work.

This International Women’s Day, we’re featuring more than a week’s worth of posts that highlight female builders and leaders. We’re showcasing women in the industry who are building, creating, and, above all, inspiring, empowering, and encouraging everyone—especially women and girls—in tech.

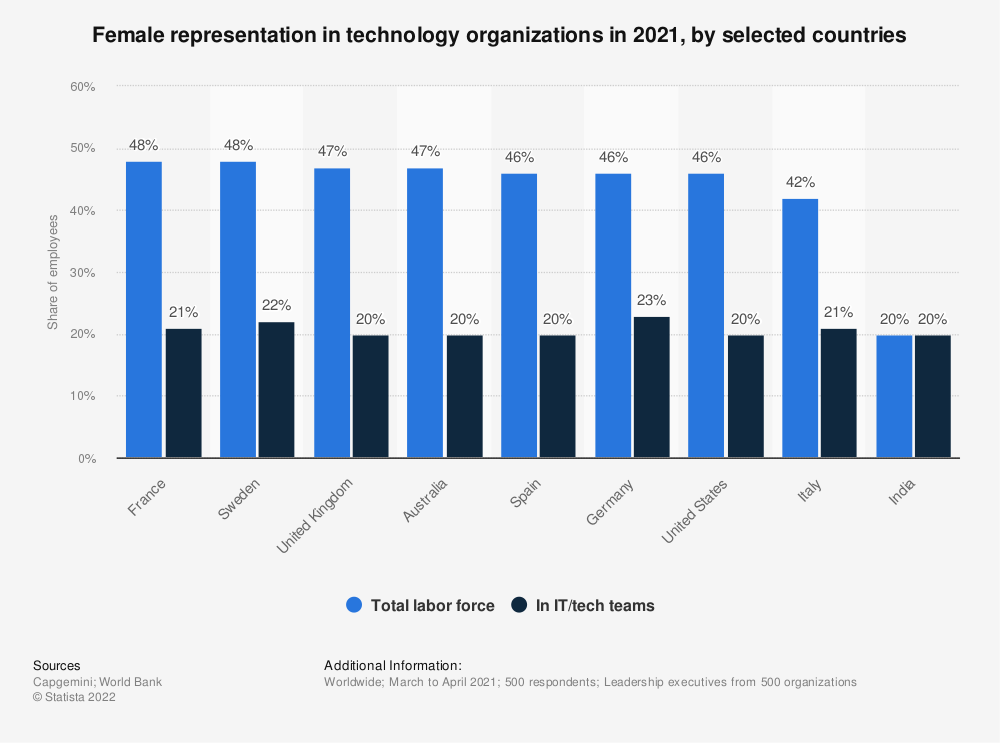
Though the number of women in tech roles is slowly increasing, they are still underrepresented. As shown in the graph that follows, women worldwide hold, on average, 21% of IT and technical roles.

Female representation in technology organizations in 2021, selected countries

Female representation in technology organizations in 2021, selected countries

This number drops to 12% when you look at cloud computing roles like Developers/Engineers, Data Engineers, System Administrators, DevOps Engineers, and Architects.

Share of male and female workers across professional clusters

Share of male and female workers across professional clusters

The technology industry has a challenge—but also an opportunity—when it comes to equal gender representation. By highlighting the work that women are doing right now to slowly but steadily change what it looks like (literally and figuratively) to work in tech and with continued commitment and effort, we can create a path to success for everyone.

She Builds Tech Skills re:Invent Roundup

AWS She Builds Tech Skills is a skill development program aimed for builders and cloud enthusiasts to create an inclusive environment to learn and develop cloud skills. Their mission is to build a community with world class leaders and influence diversity representation amongst technical roles in technology.

To kick off this week, we’re featuring a video from She Builds Tech Skills, hosted by Mai Nishitani and May Kyaw, Solutions Architects at AWS. In the video, they chat with six female Solutions Architects from around the world about their favorite services and features from re:Invent 2021, and they give advice on how to get started using these services in your architectures.

As a bonus, Mai and May followed up with these women to chat about how they’re celebrating International Women’s Day this week and every week.

Poornima Chand, Senior Solutions ArchitectPoornima Chand

Poornima Chand is a Senior Solutions Architect in the Strategic Accounts Solutions team at AWS. She works with customers to help solve their unique challenges using AWS technology solutions. She enjoys architecting and building scalable solutions. Her focus areas include Serverless, High Performance Computing and Machine Learning.

How does she encourage and mentor women in tech and beyond? Poornima is an active mentor in the AWS She Builds CloudUp program. She loves to celebrate women’s achievements and plans to spend International Women’s Day interacting with and learning from Women@Amazon and women from customer teams.

Ai-Linh Le, Solutions ArchitectAi-Linh Li

Ai-Linh Le is a Solutions Architect based in Sydney, Australia. She started her career as a software engineer and still likes to be hands-on in developing and building solutions and demos. She enjoys working with customers and helping them to build solutions and solve challenges. Her areas of focus include data analytics, machine learning, and DevOps.

How does she encourage and mentor women in tech and beyond? Ai-Linh is passionate about continuous learning and exploring new technologies, and is a mentor in the AWS She Builds CloudUp program.

Nelli Lovchikova, Enterprise Solutions ArchitectNelli Lovchikova

Nelli has nearly twenty years of experience helping companies build amazing things as a software engineer and architect. She strongly believes in engineering excellence and continuous learning and improvement.

How does she encourage and mentor women in tech and beyond? Nelli constantly researches and experiments with bleeding-edge technologies and ideas and is always happy to take other people on that journey with me, share my findings, and inspiration.

Natalie White, Enterprise Solutions ArchitectNatalie White

Natalie White is an Enterprise Solutions Architect in southern California. Her 15-year software development career across four industry verticals prior to joining AWS and her advocacy for AWS Developer Tools and Infrastructure as Code services help her earn trust with her customers’ builders and executive stakeholders and accelerate their time to done.

How does she encourage and mentor women in tech and beyond? Natalie is an active member in the Society of Women Engineers and a leader of her daughter’s Girl Scout troop, so she will celebrate International Women’s Day with Women@Amazon and across engineering domains, industry verticals, and age groups.

Deval Parikh. Senior Enterprise Solutions ArchitectDeval S Parikh

Deval Parikh is a Sr Enterprise Solutions Architect at AWS based out of Los Angeles. She is passionate about helping enterprises re-imagine their businesses in the cloud by leading them with strategic architectural guidance and building prototypes as an AWS expert.

How does she encourage and mentor women in tech and beyond? Deval is passionate about helping women STEM roles. She leads various affinity groups in AWS North America, including Women At Solutions Architecture and YouthTech. On weekends, she teaches high school and middle school students programming in Python and Spark. Outside of work, she loves to paint with oil on canvas and hiking with her friends. You can view some of her artwork at www.devalparikh.com.

Viktoria Semaan, Senior Partner Solutions ArchitectSemaan

As a Senior Partner Solutions Architect, Viktoria is helping AWS Strategic ISV Partners to build joint innovative solutions on AWS. She has 13+ years of experience in solutions architecture, leading multi-site automation and transformation projects. She is a public speaker and content creator and often shares learning opportunities on social media.

How does she encourage and mentor women in tech and beyond? Viktoria is passionate about coaching, talent development, and mentoring others. She is a mentor at the AWS She Builds CloudUp program, which focuses on empowering women and helps them to learn AWS services and products and become AWS Certified.

Would you like to know more?

If you want to hear more about AWS She Builds Tech Skills, please reach out to May or Mai on LinkedIn for more information, subscribe to their YouTube channel for the latest videos.

We’ve got more content for International Women’s Day!

Tomorrow we have a technical post, Deploying service-mesh-based architectures using AWS App Mesh and Amazon ECS from Kesha Williams, an AWS Hero and award-winning software engineer.

Later this week, we’ll share:

  • A collection of several blog posts written and co-authored by women
  • Curated content from the Let’s Architect! team and a live Twitter chat
  • A post on Women at AWS – Diverse Backgrounds, Common Goal of Becoming Solutions Architects
  • Another post on Building your brand as a SA

Enjoy!

Other ways to participate

SOC reports now available in Spanish

Post Syndicated from Rodrigo Fiuza original https://aws.amazon.com/blogs/security/soc-reports-now-available-in-spanish/

At Amazon Web Services (AWS), we continue to listen to our customers, regulators, and stakeholders to understand their needs regarding audit, assurance, certification, and attestation programs. We are pleased to announce that Fall 2021 AWS SOC 1, SOC 2 and SOC 3 reports are now available in Spanish. These translated reports will help drive greater engagement and alignment with customer and regulatory requirements across Latin America and Spain.

The English language version of the reports should be taken into account regarding the independent opinion issued by the auditors and control test results. They will be a complement to the Spanish version.

Translated SOC Reports in Spanish are available through AWS Artifact. Translated SOC reports in Spanish will be published twice a year in alignment with the Fall and Spring reporting cycles.

We value your feedback and questions—feel free to reach out to our team or give feedback about this post through the Contact Us page.

If you have feedback about this post, submit comments in the Comments section below.

Want more AWS Security news? Follow us on Twitter.


Los informes SOC ahora están disponibles en español

Seguimos escuchando a nuestros clientes, reguladores y partes interesadas para comprender sus necesidades en relación con los programas de auditoría, garantía, certificación y atestación en Amazon Web Services (AWS). Nos complace anunciar que los informes SOC 1, SOC 2 y SOC 3 de AWS de otoño de 2021 ya están disponibles en español. Estos informes traducidos ayudarán a impulsar un mayor compromiso y alineación con los requisitos regulatorios y de los clientes en las regiones de América Latina y España.

La versión en inglés de los informes debe tenerse en cuenta en relación con la opinión independiente emitida por los auditores y los resultados de las pruebas de control, como complemento de las versiones en español.

Los informes SOC traducidos en español están disponibles en AWS Artifact. Los informes SOC traducidos en español se publicarán dos veces al año según los ciclos de informes de otoño y primavera.

Valoramos sus comentarios y preguntas; no dude en ponerse en contacto con nuestro equipo o enviarnos sus comentarios sobre esta publicación a través de nuestra página Contáctenos.

Si tienes comentarios sobre esta publicación, envíalos en la sección Comentarios a continuación.

¿Desea obtener más noticias sobre seguridad de AWS? Síguenos en Twitter.
 

Rodrigo Fiuza

Rodrigo Fiuza

Rodrigo is a Security Audit Manager at AWS, based in São Paulo. He leads audits, attestations, certifications, and assessments across Latin America, Caribbean and Europe. Rodrigo has previously worked in risk management, security assurance, and technology audits for the past 12 years.

Author

Nimesh Ravasa

Nimesh is a Compliance Program Manager at Amazon Web Services. He leads multiple security and privacy initiatives within AWS. Nimesh has 14 years of experience in information security and holds CISSP, CISA, PMP, CSX, AWS Solution Architect – Associate, and AWS Security Specialty certifications.

Emma Zhang

Emma Zhang

Emma is a Compliance Program Manager at Amazon Web Services. She leads multiple process improvement projects across multiple compliance programs within AWS. Emma has 8 years of experience in risk management, IT risk assurance, and technology risk advisory.

New Amazon RDS for MySQL & PostgreSQL Multi-AZ Deployment Option: Improved Write Performance & Faster Failover

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/amazon-rds-multi-az-db-cluster/

Today, we are announcing a new Amazon Relational Database Service (RDS) Multi-AZ deployment option with up to 2x faster transaction commit latency, automated failovers typically under 35 seconds, and readable standby instances.

Amazon RDS offers two replication options to enhance availability and performance:

  • Multi-AZ deployments gives high availability and automatic failover. Amazon RDS creates a storage-level replica of the database in a second Availability Zone. It then synchronously replicates data from the primary to the standby DB instance for high availability. The primary DB instance serves application requests, while the standby DB instance remains ready to take over in case of a failure. Amazon RDS manages all aspects of failure detection, failover, and repair actions so the applications using the database can be highly available.
  • Read replicas allow applications to scale their read operations across multiple database instances. The database engine replicates data asynchronously to the read replicas. The application sends the write requests (INSERT, UPDATE, and DELETE) to the primary database, and read requests (SELECT) can be load balanced across read replicas. In case of failure of the primary node, you can manually promote a read replica to become the new primary database.

Multi-AZ deployments and read replicas serve different purposes. Multi-AZ deployments give your application high availability, durability, and automatic failover. Read replicas give your applications read scalability.

But what about applications that require both high availability with automatic failover and read scalability?

Introducing the New Amazon RDS Multi-AZ Deployment Option With Two Readable Standby Instances.
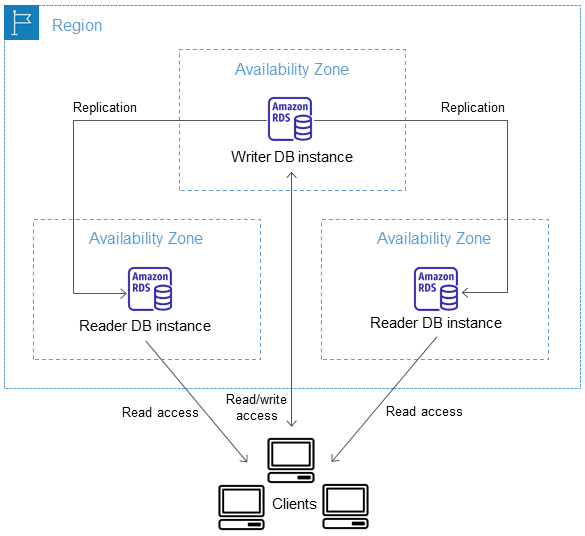
Starting today, we’re adding a new option to deploy RDS databases. This option combines automatic failover and read replicas: Amazon RDS Multi-AZ with two readable standby instances. This deployment option is available for MySQL and PostgreSQL databases. This is a database cluster with one primary and two readable standby instances. It provides up to 2x faster transaction commit latency and automated failovers, typically under 35 seconds.

The following diagram illustrates such a deployment:

Three AZ RDS databases

When the new Multi-AZ DB cluster deployment option is enabled, RDS configures a primary database and two read replicas in three distinct Availability Zones. It then monitors and enables failover in case of failure of the primary node.

Just like with traditional read replicas, the database engine replicates data between the primary node and the read replicas. And just like with the Multi-AZ one standby deployment option, RDS automatically detects and manages failover for high availability.

You do not have to choose between high availability or scalability; Multi-AZ DB cluster with two readable standby enables both.

What Are the Benefits?
This new deployment option offers you four benefits over traditional multi-AZ deployments: improved commit latency, faster failover, readable standby instances, and optimized replications.

First, write operations are faster when using Multi-AZ DB cluster. The new Multi-AZ DB cluster instances leverage M6gd and R6gd instance types. These instances are powered by AWS Graviton2 processors. They are equipped with fast NVMe SSD for local storage, ideal for high speed and low-latency storage. They deliver up to 40 percent better price performance and 50 percent more local storage GB per vCPU over comparable x86-based instances.

Multi-AZ DB instances use Amazon Elastic Block Store (EBS) to store the data and the transaction log. The new Multi-AZ DB cluster instances use local storage provided by the instances to store the transaction log. Local storage is optimized to deliver low-latency, high I/O operations per second (IOPS) to applications. Write operations are first written to the local storage transaction log, then flushed to permanent storage on database storage volumes.

Second, failover operations are typically faster than in the Multi-AZ DB instance scenario. The read replicas created by the new Multi-AZ DB cluster are full-fledged database instances. The system is designed to fail over as quickly as 35 seconds, plus the time to apply any pending transaction log. In case of failover, the system is fully automated to promote a new primary and reconfigure the old primary as a new reader instance.

Third, the two standby instances are hot standbys. Your applications may use the cluster reader endpoint to send their read requests (SELECT) to these standby instances. It allows your application to spread the database read load equally between the instances of the database cluster.

And finally, leveraging local storage for transaction log optimizes replication. The existing Multi-AZ DB instance replicates all changes at storage-level. The new Multi-AZ DB cluster replicates only the transaction log and uses a quorum mechanism to confirm at least one standby acknowledged the change. Database transactions are committed synchronously when one of the secondary instances confirms the transaction log is written on its local disk.

Migrating Existing Databases
For those of you having existing RDS databases and willing to take advantage of this new Multi-AZ DB cluster deployment option, you may take a snapshot of your database to create a storage-level backup of your existing database instance. Once the snapshot is ready, you can create a new database cluster, with Multi-AZ DB cluster deployment option, based on this snapshot. Your new Multi-AZ DB cluster will be a perfect copy of your existing database.

Let’s See It in Action
To get started, I point my browser to the AWS Management Console and navigate to RDS. The Multi-AZ DB cluster deployment option is available for MySQL version 8.0.28 or later and PostgreSQL version 13.4 R1 and 13.5 R1. I select either database engine, and I ensure the version matches the minimum requirements. The rest of the procedure is the same as a standard Amazon RDS database launch.

Under Deployment options, I select PostgreSQL, version 13.4 R1, and under Availability and Durability, I select Multi-AZ DB cluster.

Three AZ RDS launch console

If required, I may choose the set of Availability Zones RDS uses for the cluster. To do so, I create a DB subnet group and assign the cluster to this subnet group.

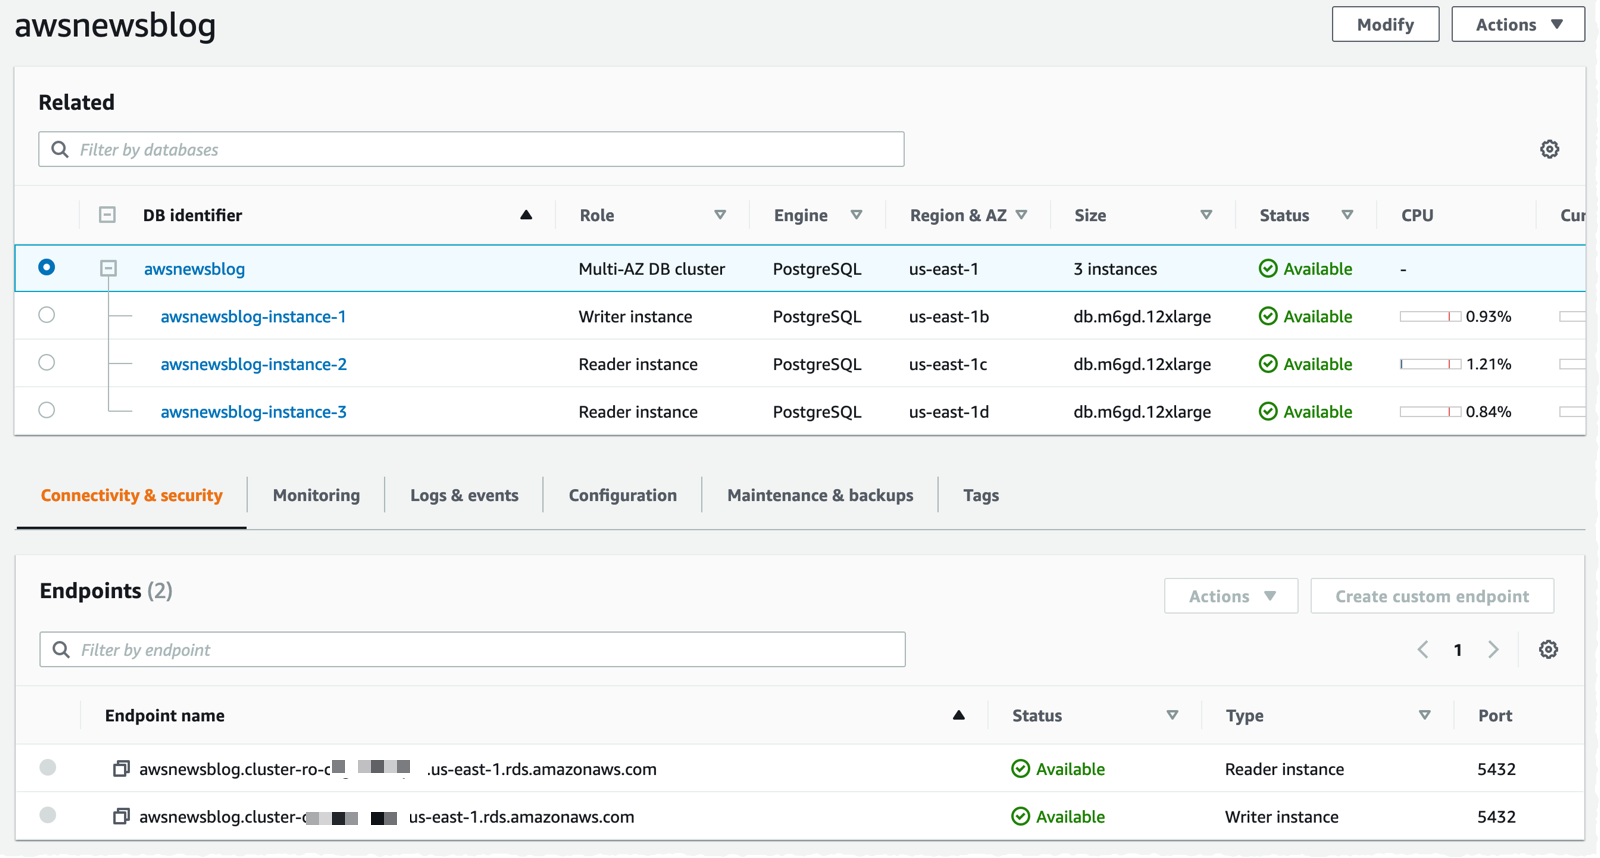
Once launched, I verify that three DB instances have been created. I also take note of the two endpoints provided by Amazon RDS: the primary endpoint and one load-balanced endpoint for the two readable standby instances.

RDS Three AZ list of instances

To test the new cluster, I create an Amazon Linux 2 EC2 instance in the same VPC, within the same security group as the database, and I make sure I attach an IAM role containing the AmazonSSMManagedInstanceCore managed policy. This allows me to connect to the instance using SSM instead of SSH.

Once the instance is started, I use SSM to connect to the instance. I install PostgreSQL client tools.

sudo amazon-linux-extras enable postgresql13
sudo yum clean metadata
sudo yum install postgresql

I connect to the primary DB. I create a table and INSERT a record.

psql -h awsnewsblog.cluster-c1234567890r.us-east-1.rds.amazonaws.com -U postgres

postgres=> create table awsnewsblogdemo (id int primary key, name varchar);
CREATE TABLE

postgres=> insert into awsnewsblogdemo (id,name) values (1, 'seb');
INSERT 0 1

postgres=> exit

To verify the replication works as expected, I connect to the read-only replica. Notice the -ro- in the endpoint name. I check the table structure and enter a SELECT statement to confirm the data have been replicated.

psql -h awsnewsblog.cluster-ro-c1234567890r.us-east-1.rds.amazonaws.com -U postgres

postgres=> \dt

              List of relations
 Schema |      Name       | Type  |  Owner
--------+-----------------+-------+----------
 public | awsnewsblogdemo | table | postgres
(1 row)

postgres=> select * from awsnewsblogdemo;
 id | name
----+------
  1 | seb
(1 row)

postgres=> exit

In the scenario of a failover, the application will be disconnected from the primary database instance. In that case, it is important that your application-level code try to reestablish network connection. After a short period of time, the DNS name of the endpoint will point to the standby instance, and your application will be able to reconnect.

To learn more about Multi-AZ DB clusters, you can refer to our documentation.

Pricing and Availability
Amazon RDS Multi-AZ deployments with two readable standbys is generally available in the following Regions: US East (N. Virginia), US West (Oregon), and Europe (Ireland). We will add more regions to this list.

You can use it with MySQL version 8.0.28 or later, or PostgreSQL version 13.4 R1 or 13.5 R1.

Pricing depends on the instance type. In US regions, on-demand pricing starts at $0.522 per hour for M6gd instances and $0.722 per hour for R6gd instances. As usual, the Amazon RDS pricing page has the details for MySQL and PostgreSQL.

You can start to use it today.

New – Customer Carbon Footprint Tool

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/new-customer-carbon-footprint-tool/

Carbon is the fourth-most abundant element in the universe, and is also a primary component of all known life on Earth. When combined with oxygen it creates carbon dioxide (CO2). Many industrial activities, including the burning of fossil fuels such as coal and oil, release CO2 into the atmosphere and cause climate change.

As part of Amazon’s efforts to increase sustainability and reduce carbon emissions, we co-founded The Climate Pledge in 2019. Along with the 216 other signatories to the Pledge, we are committed to reaching net-zero carbon by 2040, 10 years ahead of the Paris Agreement. We are driving carbon out of our business in a multitude of ways, as detailed on our Carbon Footprint page. When I share this information with AWS customers, they respond positively. They now understand that running their applications in AWS Cloud can help them to lower their carbon footprint by 88% (when compared to the enterprise data centers that were surveyed), as detailed in The Carbon Reduction Opportunity of Moving to Amazon Web Services, published by 451 Research.

In addition to our efforts, organizations in many industries are working to set sustainability goals and to make commitments to reach them. In order to help them to measure progress toward their goals they are implementing systems and building applications to measure and monitor their carbon emissions data.

Customer Carbon Footprint Tool
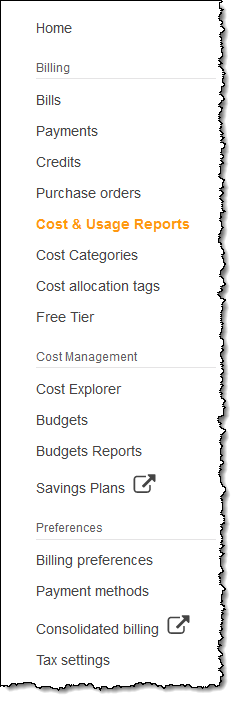
After I share information about our efforts to decarbonize with our customers, they tell me that their organization is on a similar path, and that they need to know more about the carbon footprint of their cloud infrastructure. Today I am happy to announce the new Customer Carbon Footprint Tool. This tool will help you to meet your own sustainability goals, and is available to all AWS customers at no cost. To access the calculator, I open the AWS Billing Console and click Cost & Usage Reports:

Then I scroll down to Customer Carbon Footprint Tool and review the report:

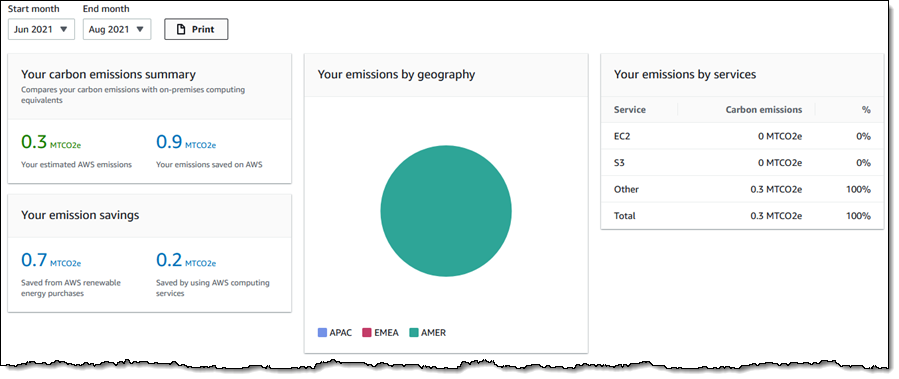
Let’s review each section. The first one allows me to select a time period with month-level granularity, and shows my carbon emissions in summary, geographic, and per-service form. In all cases, emissions are in Metric Tons of Carbon Dioxide Equivalent, abbreviated as MTCO2e:

All of the values in this section reflect the selected time period. In this example (all of which is sample data), my AWS resources emit an estimated 0.3 MTCO2e from June to August of 2021. If I had run the same application in my own facilities instead of in the AWS Cloud, I would have used an additional 0.9 MTCO2e. Of this value, 0.7 MTCO2e was saved due to renewable energy purchases made by AWS, and an additional 0.2 MTCO2e was saved due to the fact that AWS uses resources more efficiently.

I can also see my emissions by geography (all in America for this time period), and by AWS service in this section.

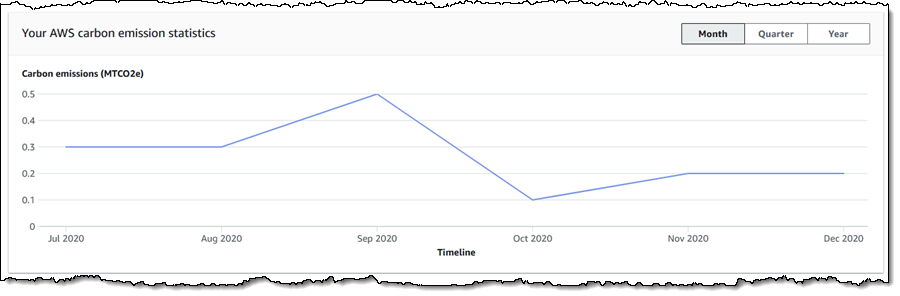
The second section shows my carbon emission statistics on a monthly, quarterly, or annual basis:

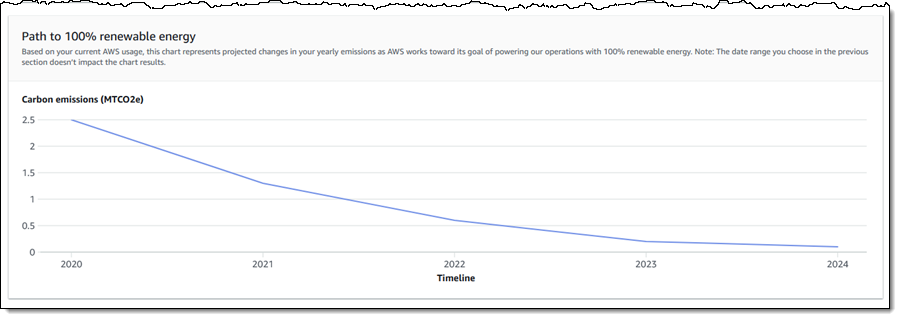
The third and final section projects how the AWS path to 100% renewable energy for our data centers will have a positive effect on my carbon emissions over time:

If you are an AWS customer, then you are already benefiting from our efforts to decarbonize and to reach 100% renewable energy usage by 2025, five years ahead of our original target.

You should also take advantage of the new Sustainability Pillar of AWS Well-Architected. This pillar contains six design principles for sustainability in the cloud, and will show you how to understand impact and to get the best utilization from the minimal number of necessary resources, while also reducing downstream impacts.

Things to Know
Here are a couple of important facts to keep in mind:

Regions – The emissions displayed reflect your AWS usage in all commercial AWS regions.

Timing – Emissions are calculated monthly. However, there is a three month delay due to the underlying billing cycle of the electric utilities that supply us with power.

Scope – The calculator shows Scope 1 and Scope 2 emissions, as defined here.

— Jeff;

AWS achieves FedRAMP P-ATO for 15 services in the AWS US East/West and AWS GovCloud (US) Regions

Post Syndicated from Alexis Robinson original https://aws.amazon.com/blogs/security/aws-achieves-fedramp-p-ato-for-15-services-in-the-aws-us-east-west-and-aws-govcloud-us-regions/

AWS is pleased to announce that 15 additional AWS services have achieved Provisional Authority to Operate (P-ATO) from the Federal Risk and Authorization Management Program (FedRAMP) Joint Authorization Board (JAB).

AWS is continually expanding the scope of our compliance programs to help customers use authorized services for sensitive and regulated workloads. AWS now offers 111 AWS services authorized in the AWS US East/West Regions under FedRAMP Moderate Authorization, and 91 services authorized in the AWS GovCloud (US) Regions under FedRAMP High Authorization.

Figure 1. Newly authorized services list

Figure 1. Newly authorized services list

Descriptions of AWS Services now in FedRAMP P-ATO

These additional AWS services now provide the following capabilities for the U.S. federal government and customers with regulated workloads:

  • Amazon Detective simplifies analyzing, investigating, and quickly identifying the root cause of potential security issues or suspicious activities. Amazon Detective automatically collects log data from your AWS resources, and uses machine learning, statistical analysis, and graph theory to build a linked set of data enabling you to easily conduct faster and more efficient security investigations.
  • Amazon FSx for Lustre provides fully managed shared storage with the scalability and performance of the popular Lustre file system.
  • Amazon FSx for Windows File Server provides fully managed shared storage built on Windows Server, and delivers a wide range of data access, data management, and administrative capabilities.
  • Amazon Kendra is an intelligent search service powered by machine learning (ML).
  • Amazon Keyspaces (for Apache Cassandra) is a scalable, highly available, and managed Apache Cassandra-compatible database service.
  • Amazon Lex is an AWS service for building conversational interfaces into applications using voice and text.
  • Amazon Macie is a fully managed data security and data privacy service that uses machine learning and pattern matching to discover and protect your sensitive data in AWS.
  • Amazon MQ is a managed message broker service for Apache ActiveMQ and RabbitMQ that simplifies setting up and operating message brokers on AWS.
  • AWS CloudHSM is a cloud-based hardware security module (HSM) that lets you generate and use your own encryption keys on the AWS Cloud.
  • AWS Cloud Map is a cloud resource discovery service. With Cloud Map, you can define custom names for your application resources, and CloudMap maintains the updated location of these dynamically changing resources.
  • AWS Glue DataBrew is a new visual data preparation tool that lets data analysts and data scientists quickly clean and normalize data to prepare it for analytics and machine learning.
  • AWS Outposts (hardware excluded) is a fully managed service that extends AWS infrastructure, services, APIs, and tools to customer premises. By providing local access to AWS managed infrastructure, AWS Outposts enables you to build and run applications on premises using the same programming interfaces used in AWS Regions, while using local compute and storage resources for lower latency and local data processing needs.
  • AWS Resource Groups grants you the ability to organize your AWS resources, managing and automating tasks for large numbers of resources at the same time.
  • AWS Snowmobile is an Exabyte-scale data transfer service used to move extremely large amounts of data to AWS. You can transfer up to 100PB per Snowmobile, a 45-foot long ruggedized shipping container, pulled by a semi-trailer truck. After an initial assessment, a Snowmobile will be transported to your data center and AWS personnel will configure it so it can be accessed as a network storage target. After you load your data, the Snowmobile is driven back to an AWS regional data center, where AWS imports the data into Amazon Simple Storage Service (Amazon S3).
  • AWS Transfer Family securely scales your recurring business-to-business file transfers to Amazon S3 and Amazon Elastic File System (Amazon EFS) using SFTP, FTPS, and FTP protocols.

The following services are now listed on the FedRAMP Marketplace and the AWS Services in Scope by Compliance Program page.

Service authorizations by Region

Service FedRAMP Moderate in AWS US East/West FedRAMP High in AWS GovCloud (US)
Amazon Detective ✓
Amazon FSx for Lustre ✓ ✓
Amazon FSx for Windows File Server ✓ ✓
Amazon Kendra ✓
Amazon Keyspaces (for Apache Cassandra) ✓
Amazon Lex ✓
Amazon Macie ✓
Amazon MQ ✓
AWS CloudHSM ✓
AWS Cloud Map ✓
AWS Glue DataBrew ✓
AWS Outposts ✓ ✓
AWS Resource Groups ✓
AWS Snowmobile ✓
AWS Transfer Family ✓ ✓

To learn what other public sector customers are doing on AWS, see our Government, Education, and Nonprofits Case Studies and Customer Success Stories. Stay tuned for future updates on our Services in Scope by Compliance Program page. Let us know how this post will help your mission by reaching out to your AWS Account Team. Lastly, if you have feedback about this blog post, let us know in the Comments section.

Want more AWS Security news? Follow us on Twitter.

Author

Alexis Robinson

Alexis is the Head of the U.S. Government Security and Compliance Program for AWS. For over 10 years, she has served federal government clients advising on security best practices and conducting cyber and financial assessments. She currently supports the security of the AWS internal environment including cloud services applicable to AWS East/West and AWS GovCloud (US) Regions.

Happy 10th Birthday, DynamoDB! 🎉🎂🎁

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/happy-birthday-dynamodb/

On January 18th 2012, Jeff and Werner announced the general availability of Amazon DynamoDB, a fully managed flexible NoSQL database service for single-digit millisecond performance at any scale.

During the last 10 years, hundreds of thousands of customers have adopted DynamoDB. It regularly reaches new peaks of performance and scalability. For example, during the last Prime Day sales in June 2021, it handled trillions of requests over 66 hours while maintaining single-digit millisecond performance and peaked at 89.2 million requests per second. Disney+ uses DynamoDB to ingest content, metadata, and billions of viewers actions each day. Even during unprecedented demands caused by the pandemic, DynamoDB was able to help customers as many across the world had to change their way of working, needing to meet and conduct business virtually. For example, Zoom was able to scale from 10 million to 300 million daily meeting participants when we all started to make video calls in early 2020.

A decade of innovation with Amazon DynamoDB

On this special anniversary, join us for an unique online event on Twitch on March 1st. I’ll tell you more about this at the end of this post. But before talking about this event, let’s take this opportunity to reflect back on the genesis of this service and the main capabilities we added since the original launch 10 years ago.

The History Behind DynamoDB
The story of DynamoDB started long before the launch 10 years ago. It started with a series of outages on Amazon’s e-commerce platform during the holiday shopping season in 2004. At that time, Amazon was transitioning from a monolithic architecture to microservices. The design principle was (and still is) that each stateful microservice uses its own data store, and other services are required to access a microservice’s data through a publicly exposed API. Direct database access was not an option anymore. At that time, most microservices were using a relational database provided by a third-party vendor. Given the volume of traffic during the holiday season in 2004, the database system experienced some hard-to-debug and hard-to-reproduce deadlocks. The e-commerce platform was pushing the relational databases to their limits, despite the fact that we were using simple usage patterns, such as query by primary keys only. These usage patterns do not require the complexity of a relational database.

At Amazon and AWS, after an outage happens, we start a process called Correction of Error (COE) to document the root cause of the issue, to describe how we fixed it, and to detail the changes we’re making to avoid recurrence. During the COE for this database issue, a young, naïve, 20-year-old intern named Swaminathan (Swami) Sivasubramanian (now VP of the database, analytics, and ML organization at AWS) asked the question, “Why are we using a relational database for this? These workloads don’t need the SQL level of complexity and transactional guarantees.”

This led Amazon to rethink the architecture of its data stores and to build the original Dynamo database. The objective was to address the demanding scalability and reliability requirements of the Amazon e-commerce platform. This non-relational, key-value database was initially targeted at use cases that were the core of the Amazon e-commerce operations, such as the shopping basket and the session service.

AWS published the Dynamo paper in 2007, three years later, to describe our design principles and provide the lessons learned from running this database to support Amazon’s core e-commerce operations. Over the years, we saw several Dynamo clones appear, proving other companies were searching for scalable solutions, just like Amazon.

After a couple of years, Dynamo was adopted by several core service teams at Amazon. Their engineers were very satisfied with the performance and scalability. However, we started to interview engineers to understand why it was not more broadly adopted within Amazon. We learned Dynamo was giving teams the reliability, performance, and scalability they needed, but it did not simplify the operational complexity of running the system. Teams were still needed to install, configure, and operate the system in Amazon’s data centers.

At the time, AWS was proposing Amazon SimpleDB as a NoSQL service. Many teams preferred the operational simplicity of SimpleDB despite the difficulties to scale a domain beyond 10 GB, its non-predictable latency (it was affected by the size of the database and its indexes), and its eventual consistency model.

We concluded the ideal solution would combine the strengths of Dynamo—the scalability and the predictable low latency to retrieve data—with the operational simplicity of SimpleDB—just having a table to declare and let the system handle the low-level complexity transparently.

DynamoDB was born.

DynamoDB frees developers from the complexity of managing hardware and software. It handles all the complexity of scaling partitions and re-partitions your data to meet your throughput requirements. It scales seamlessly without the need to manually re-partition tables, and it provides predictable low latency access to your data (single-digit milliseconds).

At AWS, the moment we launch a new service is not the end of the project. It is actually the beginning. Over the last 10 years, we have continuously listened to your feedback, and we have brought new capabilities to DynamoDB. In addition to hundreds of incremental improvements, we added:

… and many more.

Lastly, during the last AWS re:Invent conference, we announced Amazon DynamoDB Standard-Infrequent Access (DynamoDB Standard-IA). This new DynamoDB table class allows you to lower the cost of data storage for infrequently accessed data by 60%. The ideal use case is for data that you need to keep for the long term and that your application needs to occasionally access, without compromising on access latency. In the past, to lower storage costs for such data, you were writing code to move infrequently accessed data to lower-cost storage alternatives, such as Amazon Simple Storage Service (Amazon S3). Now you can switch to the DynamoDB Standard-IA table class to store infrequently accessed data while preserving the high availability and performance of DynamoDB.

How To Get Started
To get started with DynamoDB, as a developer, you can refer to the Getting Started Guide in our documentation or read the excellent DynamoDB, Explained, written by Alex DeBrie, one of our AWS Heroes, and author of The DynamoDB Book. To dive deep into DynamoDB data modeling, AWS Hero Jeremy Daly is preparing a video course “DynamoDB Modeling for the rest of us“.

Customers now leverage DynamoDB across virtually any industry vertical, geographic area, and company size. You are continually surprising us with how you innovate on DynamoDB, and you are continually pushing us to continue to evolve DynamoDB to make it easier to build the next generation of applications. We are going to continue to work backwards from your feedback to meet your ever evolving needs and to enable you to innovate and scale for decades to come.

A Decade of Innovation with DynamoDB – A Virtual Event
As I mentioned at the beginning, we also would love to celebrate this anniversary with you. We prepared a live Twitch event for you to learn best practices, see technical demos, and attend a live Q&A. You will hear stories from two of our long-time customers : SmugMug CEO Don MacAskill, and engineering leaders from Dropbox. In addition, you’ll get a chance to ask your questions to and chat with AWS’ blog legend and Chief Evangelist Jeff Barr, and DynamoDB‘s product managers and engineers. Finally, AWS heroes Alex DeBrie and Jeremy Daly will host two deep dive technical sessions. Have a look at the full agenda here.

This will be live on Twitch on March 1st, you can register today. The first 1,000 registrants from US will receive a free digital copy of the DynamoDB book (this has a $79 retail value).

To DynamoDB’s next 10 years. Cheers 🥂.

— seb

Introducing s2n-quic, a new open-source QUIC protocol implementation in Rust

Post Syndicated from Panos Kampanakis original https://aws.amazon.com/blogs/security/introducing-s2n-quic-open-source-protocol-rust/

At Amazon Web Services (AWS), security, high performance, and strong encryption for everyone are top priorities for all our services. With these priorities in mind, less than a year after QUIC ratification in the Internet Engineering Task Force (IETF), we are introducing support for the QUIC protocol which can boost performance for web applications that currently use Transport Layer Security (TLS) over Transmission Control Protocol (TCP). We are pleased to announce the availability of s2n-quic, an open-source Rust implementation of the QUIC protocol added to our set of AWS encryption open-source libraries.

What is QUIC?

QUIC is an encrypted transport protocol designed for performance and is the foundation of HTTP/3. It is specified in a set of IETF standards ratified in May 2021. QUIC protects its UDP datagrams by using encryption and authentication keys established in a TLS 1.3 handshake carried over QUIC transport. It is designed to improve upon TCP by providing improved first-byte latency and handling of multiple streams, and solving issues such as head-of-line blocking, mobility, and data loss detection. This enables web applications to perform faster, especially over poor networks. Other potential uses include latency-sensitive connections and UDP connections currently using DTLS, which now can run faster.

Renaming s2n

AWS has long supported open-source encryption libraries; in 2015 we introduced s2n as a TLS library. The name s2n is short for signal to noise, and is a nod to the almost magical act of encryption—disguising meaningful signals, like your critical data, as seemingly random noise.

Now that AWS introduces our new QUIC open-source library, we are renaming s2n to s2n-tls. s2n-tls is an efficient TLS library built over other crypto libraries like OpenSSL libcrypto or AWS libcrypto (AWS-LC). AWS-LC is a general-purpose cryptographic library maintained by AWS which originated from the Google project BoringSSL. The s2n family of AWS encryption open-source libraries now consists of s2n-tls, s2n-quic, and s2n-bignum. s2n-bignum is a collection of bignum arithmetic routines maintained by AWS designed for crypto applications.

s2n-quic details

Similar to s2n-tls, s2n-quic is designed to be small and fast, with simplicity as a priority. It is written in Rust, so it reaps some of its benefits such as performance, thread and memory-safety. s2n-quic depends either on s2n-tls or rustls for the TLS 1.3 handshake.

The main advantages of s2n-quic are:

  • Simple API. For example, a QUIC echo server-example can be built with just a few API calls.
  • Highly configurable. s2n-quic is configured with code through providers that allow an application to granularly control functionality. You can see an example of the server’s simple config in the QUIC echo server-example.
  • Extensive testing. Fuzzing (libFuzzer, American Fuzzy Fop (AFL), and honggfuzz), corpus replay unit testing of derived corpus files, testing of concrete and symbolic execution engines with bolero, and extensive integration and unit testing are used to validate the correctness of our implementation.
  • Thorough interoperability testing for every code change. There are multiple public QUIC implementations; s2n-quic is continuously tested to interoperate with many of them.
  • Verified correctness, post-quantum hybrid key exchange, and maturity for the TLS handshake when built with s2n-tls.
  • Thorough compliance coverage tracking of normative language in relevant standards.

Some important features in s2n-quic that can improve performance and connection management include CUBIC congestion controller support, packet pacing, Generic Segmentation Offload (GSO) support, Path MTU Discovery, and unique connection identifiers detached from the address.

AWS is continuing to invest in encryption optimization techniques, UDP performance improvement technologies, and formal code verification with the AWS Automated Reasoning Group to further enhance the library.

Like s2n-tls, which has already been introduced in various AWS services, AWS services that need to make use of the benefits of QUIC will begin integrating s2n-quic. QUIC is a standardized protocol which, when introduced in a service like web content delivery, can improve user experience or application performance. AWS still plans to continue support for existing protocols like TLS, so existing applications will remain interoperable. Amazon CloudFront is scheduled to be the first AWS service to integrate s2n-quic with its support for HTTP/3 in 2022.

Conclusion

If you are interested in using or contributing to s2n-quic source code or documentation, they are publicly available under the terms of the Apache Software License 2.0 from our s2n-quic GitHub repository.

If you package or distribute s2n-quic or s2n-tls, or use it as part of a large multi-user service, you may be eligible for pre-notification of security issues. Please contact [email protected].

If you discover a potential security issue in s2n-quic or s2n-tls, we ask that you notify AWS Security by using our vulnerability reporting page.

Stay tuned for more topics on s2n-quic like quantum-resistance, performance analyses, uses, and other technical details.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Author

Panos Kampanakis

Panos has extensive experience on cybersecurity, applied cryptography, security automation, and vulnerability management. He has trained and presented on various security topics at technical events for numerous years, and also co-authored Cisco Press books, papers, standards, and research publications. He has participated in various security standards bodies to provide common interoperable protocols and languages for security information sharing, cryptography, and PKI. In his current role, Panos works with engineers and industry standards partners to provide cryptographically secure tools, protocols, and standards.

AWS User Guide to Financial Services Regulations and Guidelines in Switzerland and FINMA workbooks publications

Post Syndicated from Margo Cronin original https://aws.amazon.com/blogs/security/aws-user-guide-to-financial-services-regulations-and-guidelines-in-switzerland-and-finma/

AWS is pleased to announce the publication of the AWS User Guide to Financial Services Regulations and Guidelines in Switzerland whitepaper and workbooks.

This guide refers to certain rules applicable to financial institutions in Switzerland, including banks, insurance companies, stock exchanges, securities dealers, portfolio managers, trustees and other financial entities which are overseen (directly or indirectly) by the Swiss Financial Market Supervisory Authority (FINMA).

Amongst other topics, this guide covers requirements created by the following regulations and publications of interest to Swiss financial institutions:

  • Federal Laws – including Article 47 of the Swiss Banking Act (BA). Banks and Savings Banks are overseen by FINMA and governed by the BA (Bundesgesetz über die Banken und Sparkassen, Bankengesetz, BankG). Article 47 BA holds relevance in the context of outsourcing.
  • Response on Cloud Guidelines for Swiss Financial institutions produced by the Swiss Banking Union, Schweizerische Bankiervereinigung SBVg.
  • Controls outlined by FINMA, Switzerland’s independent regulator of financial markets, that may be applicable to Swiss banks and insurers in the context of outsourcing arrangements to the cloud.

In combination with the AWS User Guide to Financial Services Regulations and Guidelines in Switzerland whitepaper, customers can use the detailed AWS FINMA workbooks and ISAE 3000 report available from AWS Artifact.

The five core FINMA circulars are intended to assist Swiss-regulated financial institutions in understanding approaches to due diligence, third-party management, and key technical and organizational controls that should be implemented in cloud outsourcing arrangements, particularly for material workloads. The AWS FINMA workbooks and ISAE 3000 report scope covers, in detail, requirements of the following FINMA circulars:

  • 2018/03 Outsourcing – banks and insurers (04.11.2020)
  • 2008/21 Operational Risks – Banks – Principle 4 Technology Infrastructure (31.10.2019)
  • 2008/21 Operational Risks – Banks – Appendix 3 Handling of electronic Client Identifying Data (31.10.2019)
  • 2013/03 Auditing – Information Technology (04.11.2020)
  • 2008/10 Self-regulation as a minimum standard – Minimum Business Continuity Management (BCM) minimum standards proposed by the Swiss Insurance Association (01.06.2015) and Swiss Bankers Association (29.08.2013)

Customers can use the detailed FINMA workbooks, which include detailed control mappings for each FINMA control, covering both the AWS control activities and the Customer User Entity Controls. Where applicable, under the AWS Shared Responsibility Model, these workbooks provide industry standard practices, incorporating AWS Well-Architected, to assist Swiss customers in their own preparation for FINMA circular alignment.

This whitepaper follows the issuance of the second Swiss Financial Market Supervisory Authority (FINMA) ISAE 3000 Type 2 attestation report. The latest report covers the period from October 1, 2020 to September 30, 2021, with a total of 141 AWS services and 23 global AWS Regions included in the scope. Customers can download the report from AWS Artifact. A full list of certified services and Regions is presented within the published FINMA report.

As always, AWS is committed to bringing new services into the scope of our FINMA program in the future based on customers’ architectural and regulatory needs. Please reach out to your AWS account team if you have any questions or feedback. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Author

Margo Cronin

Margo is a Principal Security Specialist at Amazon Web Services based in Zurich, Switzerland. She spends her days working with customers, from startups to the largest of enterprises, helping them build new capabilities and accelerating their cloud journey. She has a strong focus on security, helping customers improve their security, risk, and compliance in the cloud.

New for Amazon CodeGuru Reviewer – Detector Library and Security Detectors for Log-Injection Flaws

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/new-for-amazon-codeguru-reviewer-detector-library-and-security-detectors-for-log-injection-flaws/

Amazon CodeGuru Reviewer is a developer tool that detects security vulnerabilities in your code and provides intelligent recommendations to improve code quality. For example, CodeGuru Reviewer introduced Security Detectors for Java and Python code to identify security risks from the top ten Open Web Application Security Project (OWASP) categories and follow security best practices for AWS APIs and common crypto libraries. At re:Invent, CodeGuru Reviewer introduced a secrets detector to identify hardcoded secrets and suggest remediation steps to secure your secrets with AWS Secrets Manager. These capabilities help you find and remediate security issues before you deploy.

Today, I am happy to share two new features of CodeGuru Reviewer:

  • A new Detector Library describes in detail the detectors that CodeGuru Reviewer uses when looking for possible defects and includes code samples for both Java and Python.
  • New security detectors have been introduced for detecting log-injection flaws in Java and Python code, similar to what happened with the recent Apache Log4j vulnerability we described in this blog post.

Let’s see these new features in more detail.

Using the Detector Library
To help you understand more clearly which detectors CodeGuru Reviewer uses to review your code, we are now sharing a Detector Library where you can find detailed information and code samples.

These detectors help you build secure and efficient applications on AWS. In the Detector Library, you can find detailed information about CodeGuru Reviewer’s security and code quality detectors, including descriptions, their severity and potential impact on your application, and additional information that helps you mitigate risks.

Note that each detector looks for a wide range of code defects. We include one noncompliant and compliant code example for each detector. However, CodeGuru uses machine learning and automated reasoning to identify possible issues. For this reason, each detector can find a range of defects in addition to the explicit code example shown on the detector’s description page.

Let’s have a look at a few detectors. One detector is looking for insecure cross-origin resource sharing (CORS) policies that are too permissive and may lead to loading content from untrusted or malicious sources.

Detector Library screenshot.

Another detector checks for improper input validation that can enable attacks and lead to unwanted behavior.

Detector Library screenshot.

Specific detectors help you use the AWS SDK for Java and the AWS SDK for Python (Boto3) in your applications. For example, there are detectors that can detect hardcoded credentials, such as passwords and access keys, or inefficient polling of AWS resources.

New Detectors for Log-Injection Flaws
Following the recent Apache Log4j vulnerability, we introduced in CodeGuru Reviewer new detectors that check if you’re logging anything that is not sanitized and possibly executable. These detectors cover the issue described in CWE-117: Improper Output Neutralization for Logs.

These detectors work with Java and Python code and, for Java, are not limited to the Log4j library. They don’t work by looking at the version of the libraries you use, but check what you are actually logging. In this way, they can protect you if similar bugs happen in the future.

Detector Library screenshot.

Following these detectors, user-provided inputs must be sanitized before they are logged. This avoids having an attacker be able to use this input to break the integrity of your logs, forge log entries, or bypass log monitors.

Availability and Pricing
These new features are available today in all AWS Regions where Amazon CodeGuru is offered. For more information, see the AWS Regional Services List.

The Detector Library is free to browse as part of the documentation. For the new detectors looking for log-injection flaws, standard pricing applies. See the CodeGuru pricing page for more information.

Start using Amazon CodeGuru Reviewer today to improve the security of your code.

— Danilo

New for App Runner – VPC Support

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/new-for-app-runner-vpc-support/

With AWS App Runner, you can quickly deploy web applications and APIs at any scale. You can start with your source code or a container image, and App Runner will fully manage all infrastructure including servers, networking, and load balancing for your application. If you want, App Runner can also configure a deployment pipeline for you.

Starting today, App Runner enables your services to communicate with databases and other applications hosted in an Amazon Virtual Private Cloud (VPC). For example, you can now connect App Runner services to databases in Amazon Relational Database Service (RDS), Redis or Memcached caches in Amazon ElastiCache, or your own applications running in Amazon Elastic Container Service (Amazon ECS), Amazon Elastic Kubernetes Service (EKS), Amazon Elastic Compute Cloud (Amazon EC2), or on-premises and connected via AWS Direct Connect.

Previously, in order for your App Runner application to connect to these resources, they needed to be publicly accessible over the internet. With this feature, App Runner applications can connect to private endpoints in your VPC, and you can enable a more secure and compliant environment by removing public access to these resources.

Within App Runner, you can now create VPC connectors that specify which VPC, subnets, and security groups to use for private networking. Once configured, you can use a VPC connector with one or more App Runner services.

When connected to a VPC, all outbound traffic from your AppRunner service will be routed based on the VPC routing rules. Services will not have access to the public internet (including AWS APIs) unless allowed by a route to a NAT Gateway. You can also set up VPC endpoints to connect to AWS APIs such as Amazon Simple Storage Service (Amazon S3) and Amazon DynamoDB to avoid NAT traffic.

The VPC connectors in App Runner work similarly to VPC networking in AWS Lambda and are based on AWS Hyperplane, the internal Amazon network function virtualization system behind AWS services and resources like Network Load Balancer, NAT Gateway, and AWS PrivateLink.

Let’s see how this works in practice with a web application connected to an RDS database.

Preparing the Amazon RDS Database
I start by configuring a database for my application. To simplify capacity management for this database, I use Amazon Aurora Serverless. In the RDS console, I create an Amazon Aurora MySQL-Compatible database. For the Capacity type, I choose Serverless. For networking, I use my default VPC and the default security group. I don’t need to make the database publicly accessible because I am going to connect using private VPC networking. To simplify connecting later, I enable AWS Identity and Access Management (IAM) database authentication.

I start an Amazon Linux EC2 instance in the same VPC. To connect from the EC2 instance to the database, I need a MySQL client. I install MariaDB, a community-developed branch of MySQL:

sudo yum install mariadb

Then, I connect to the database using the admin user.

mysql -h <DATABASE_HOST> -u admin -P

I enter the admin user password to log in. Then, I create a new user (bookuser) that is configured to use IAM authentication.

CREATE USER bookuser IDENTIFIED WITH AWSAuthenticationPlugin AS 'RDS'; 

I create the bookcase database and give permissions to the bookuser user to query the bookcase database.

CREATE DATABASE bookcase;
GRANT SELECT ON bookcase.* TO 'bookuser'@'%’;

To store information about some of my books, I create the authors and books tables.

CREATE TABLE authors (
  authorId INT,
  name varchar(255)
 );

CREATE TABLE books (
  bookId INT,
  authorId INT,
  title varchar(255),
  year INT
);

Then, I insert some values in the two tables:

INSERT INTO authors VALUES (1, "Issac Asimov");
INSERT INTO authors VALUES (2, "Robert A. Heinlein");
INSERT INTO books VALUES (1, 1, "Foundation", 1951);
INSERT INTO books VALUES (2, 1, "Foundation and Empire", 1952);
INSERT INTO books VALUES (3, 1, "Second Foundation", 1953);
INSERT INTO books VALUES (4, 2, "Stranger in a Strange Land", 1961);

Preparing the Application Source Code Repository
With App Runner, I can deploy a new service from code hosted in a source code repository or using a container image. In this example, I use a private project that I have on GitHub.

It’s a very simple Python web application connecting to the database I just created. This is the source code of the app (server.py):

from wsgiref.simple_server import make_server
from pyramid.config import Configurator
from pyramid.response import Response
import os
import boto3
import mysql.connector

import os

DATABASE_REGION = 'us-east-1'
DATABASE_CERT = 'cert/us-east-1-bundle.pem'
DATABASE_HOST = os.environ['DATABASE_HOST']
DATABASE_PORT = os.environ['DATABASE_PORT']
DATABASE_USER = os.environ['DATABASE_USER']
DATABASE_NAME = os.environ['DATABASE_NAME']

os.environ['LIBMYSQL_ENABLE_CLEARTEXT_PLUGIN'] = '1'

PORT = int(os.environ.get('PORT'))

rds = boto3.client('rds')

try:
    token = rds.generate_db_auth_token(
        DBHostname=DATABASE_HOST,
        Port=DATABASE_PORT,
        DBUsername=DATABASE_USER,
        Region=DATABASE_REGION
    )
    mydb =  mysql.connector.connect(
        host=DATABASE_HOST,
        user=DATABASE_USER,
        passwd=token,
        port=DATABASE_PORT,
        database=DATABASE_NAME,
        ssl_ca=DATABASE_CERT
    )
except Exception as e:
    print('Database connection failed due to {}'.format(e))          

def all_books(request):
    mycursor = mydb.cursor()
    mycursor.execute('SELECT name, title, year FROM authors, books WHERE authors.authorId = books.authorId ORDER BY year')
    title = 'Books'
    message = '<html><head><title>' + title + '</title></head><body>'
    message += '<h1>' + title + '</h1>'
    message += '<ul>'
    for (name, title, year) in mycursor:
        message += '<li>' + name + ' - ' + title + ' (' + str(year) + ')</li>'
    message += '</ul>'
    message += '</body></html>'
    return Response(message)

if __name__ == '__main__':

    with Configurator() as config:
        config.add_route('all_books', '/')
        config.add_view(all_books, route_name='all_books')
        app = config.make_wsgi_app()
    server = make_server('0.0.0.0', PORT, app)
    server.serve_forever()

The application uses the AWS SDK for Python (boto3) for IAM database authentication, the Pyramid web framework, and the MySQL connector for Python. The requirements.txt file describes the application dependencies:

boto3
pyramid==2.0
mysql-connector-python

To use SSL/TLS encryption when connecting to the database, I download a certificate bundle and add it to my source code repository.

Using VPC Support in AWS App Runner
In the App Runner console, I select Source code repository and the branch to use.

Console screenshot.

For the deployment settings, I choose Manual. Optionally, I could have selected the Automatic deployment trigger to have every push to this branch deploy a new version of my service.

Console screenshot.

Then, I configure the build. This is a very simple application, so I pass the build and start commands in the console:

Build command – pip install -r requirements.txt
Start command – python server.py

For more advanced use cases, I would add an apprunner.yaml configuration file to my repository as in this sample application.

Console screenshot.

In the service configuration, I add the environment variables used by the application to connect to the database. I don’t need to pass a database password here because I am using IAM authentication.

Console screenshot.

In the Security section, I select an IAM role that gives permissions to connect to the database using IAM database authentication as described in Creating and using an IAM policy for IAM database access.

Console screenshot.

Here’s the syntax of the IAM role. I find the database Resource ID in the Configuration tab of the RDS console.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": [
                "rds-db:connect"
            ],
            "Resource": [
                "arn:aws:rds-db:<REGION>:<ACCOUNT>:dbuser:<DB_RESOURCE_ID>/<DB_USER>"
            ]
        }
    ]
}

For the role trust policy,   I follow the instruction for instance roles in How App Runner works with IAM.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Principal": {
        "Service": "tasks.apprunner.amazonaws.com"
      },
      "Action": "sts:AssumeRole"
    }
  ]
}

For Networking, I select the new option to use a Custom VPC for outgoing network traffic and then add a new VPC connector.

Console screenshot.

To add a new VPC connector, I write down a name and then select the VPC, subnets, and security groups to use. Here, I select all the subnets of my default VPC and the default security group. In this way, the App Runner service will be able to connect to the RDS database.

Console screenshot.

The next time, when configuring another application with the same VPC networking requirements, I can just select the VPC connector I created before.

Console screenshot. I review all the settings and then create and deploy the service.

After a few minutes, the service is running, and I choose the default domain to open a new tab in my browser. The application is connected to the database using VPC networking and performs a SQL query to join the books and authors tables and provide some reading suggestions. It works!

Browser screenshot.

Availability and Pricing
VPC connectors are available in all AWS Regions where AWS App Runner is offered. For more information, see the Regional Services List. There is no additional cost for using this feature, but you pay the standard pricing for data transmission or any NAT gateway or VPC endpoints you set up. You can set up VPC connectors with the AWS Management Console, AWS Command Line Interface (CLI), AWS SDKs, and AWS CloudFormation.

With VPC connectors, you can deploy your applications using App Runner and connect them to your private databases, caches, and applications running in a VPC or on-premises and connected via AWS Direct Connect.

Build and run web applications at any scale and connect to your private VPC resources with AWS App Runner.

— Danilo

NEW – Replicate Existing Objects with Amazon S3 Batch Replication

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/aws/new-replicate-existing-objects-with-amazon-s3-batch-replication/

Starting today, you can replicate existing Amazon Simple Storage Service (Amazon S3) objects and synchronize your buckets using the new Amazon S3 Batch Replication feature.

Amazon S3 Replication supports several customer use cases. For example, you can use it to minimize latency by maintaining copies of your data in AWS Regions geographically closer to your users, to meet compliance and data sovereignty requirements, and to create additional resiliency for disaster recovery planning. S3 Replication is a fully managed, low-cost feature that replicates newly uploaded objects between buckets. The buckets can belong to the same or different accounts. Objects may be replicated to a single destination bucket or to multiple destination buckets. Destination buckets can be in different AWS Regions (Cross-Region Replication) or within the same Region as the source bucket (Same-Region Replication).

Replication flow

But until today, S3 Replication could not replicate existing objects; now you can do it with S3 Batch Replication.

There are many reasons why customers will want to replicate existing objects. For example, customers might want to copy their data to a new AWS Region for a disaster recovery setup. To do that, they will need to populate the new destination bucket with existing data. Another reason to copy existing data comes from organizations that are expanding around the world. For example, imagine a US-based animation company now opens a new studio in Singapore. To reduce latency for their employees, they will need to replicate all the internal files and in-progress media files to the Asia Pacific (Singapore) Region. One other common use case we see is customers going through mergers and acquisitions where they need to transfer ownership of existing data from one AWS account to another.

To replicate existing objects between buckets, customers end up creating complex processes. In addition, copying objects between buckets does not preserve the metadata of objects such as version ID and object creation time.

Today we are happy to launch S3 Batch Replication, a new capability offered through S3 Batch Operations that removes the need for customers to develop their own solutions for copying existing objects between buckets. It provides a simple way to replicate existing data from a source bucket to one or more destinations. With this capability, you can replicate any number of objects with a single job.

When to Use Amazon S3 Batch Replication
S3 Batch Replication can be used to:

  • Replicate existing objects – use S3 Batch Replication to replicate objects that were added to the bucket before the replication rules were configured.
  • Replicate objects that previously failed to replicate – retry replicating objects that failed to replicate previously with the S3 Replication rules due to insufficient permissions or other reasons.
  • Replicate objects that were already replicated to another destination – you might need to store multiple copies of your data in separate AWS accounts or Regions. S3 Batch Replication can replicate objects that were already replicated to new destinations.
  • Replicate replicas of objects that were created from a replication rule – S3 Replication creates replicas of objects in destination buckets. Replicas of objects cannot be replicated again with live replication. These replica objects can only be replicated with S3 Batch Replication.

Get started with S3 Batch Replication
There are many ways to get started with S3 Batch Replication from the S3 console. You can create a job from the Replication configuration page or the Batch Operations create job page. You will also get prompted to replicate existing objects when you create a new replication rule or add a new destination bucket.

For this demo, imagine that you are creating a replication rule in a bucket that has existing objects. When you finish creating the rule, you will get prompted with a message asking you if you want to replicate existing objects.

Prompt asking if you want to replicate existing objects

If you answer yes, then you will be directed to a simplified Create Batch Operations job page. If you want this job to execute automatically after the job is ready, you can leave the default option. If you want to review the manifest or the job details before running the job, select Wait to run the job when it’s ready.

This method of creating the job automatically generates the manifest of objects to replicate. A manifest is a list of objects in a given source bucket to apply the replication rules. The generated manifest report has the same format as an Amazon S3 Inventory Report.

Create a Batch Operations job view

S3 Batch Replication creates a Completion report, similar to other Batch Operations jobs, with information on the results of the replication job. It is highly recommended to select this option and to specify a bucket to store this report.

Completion report configuration

The final step is to configure permissions for creating this batch job. If you keep the default settings, Amazon S3 will create a new AWS Identity and Access Management (IAM) role for you.

Permissions configurations

After you save this job, check the status of the job on the Batch Operations page. You will see the job changing status as it progresses, the percentage of files that have been replicated, and the total number of files that have failed the replication.

Keep in mind that existing objects can take longer to replicate than new objects, and the replication speed largely depends on the AWS Regions, size of data, object count, and encryption type.

Job status page

When the Batch Replication job completes, you can navigate to the bucket where you saved the completion report to check the status of object replication. The reports have the same format as an Amazon S3 Inventory Report.

Finding the report and manifest

Pricing and availability
When using this feature, you will be charged replication fees for request and data transfer for cross Region, for the
batch operations, and a manifest generation fee if you opted for it.

Additionally, you will be charged the storage cost of storing the replicated data in the destination bucket and AWS KMS charges if your objects are replicated with AWS KMS. Check the Replication tab on the S3 pricing page to learn all the details.

S3 Batch Replication is available in all AWS Regions, including the AWS GovCloud Regions, the AWS China (Beijing) Region, operated by Sinnet, and the AWS China (Ningxia) Region, operated by NWCD. And you can get started using the Amazon S3 console, CLI, S3 API, or AWS SDKs client.

To learn more about S3 Batch Replication, check out the Amazon S3 User Guide.

— Marcia