Tag Archives: AWS Lambda

Throttling a tiered, multi-tenant REST API at scale using API Gateway: Part 2

Post Syndicated from Nick Choi original https://aws.amazon.com/blogs/architecture/throttling-a-tiered-multi-tenant-rest-api-at-scale-using-api-gateway-part-2/

In Part 1 of this blog series, we demonstrated why tiering and throttling become necessary at scale for multi-tenant REST APIs, and explored tiering strategy and throttling with Amazon API Gateway.

In this post, Part 2, we will examine tenant isolation strategies at scale with API Gateway and extend the sample code from Part 1.

Enhancing the sample code

To enable this functionality in the sample code (Figure 1), we will make manual changes. First, create one API key for the Free Tier and five API keys for the Basic Tier. Currently, these API keys are private keys for your Amazon Cognito login, but we will make a further change in the backend business logic that will promote them to pooled resources. Note that all of these modifications are specific to this sample code’s implementation; the implementation and deployment of a production code may be completely different (Figure 1).

Cloud architecture of the sample code

Figure 1. Cloud architecture of the sample code

Next, in the business logic for thecreateKey(), find the AWS Lambda function in lambda/create_key.js.  It appears like this:

function createKey(tableName, key, plansTable, jwt, rand, callback) {
  const pool = getPoolForPlanId( key.planId ) 
  if (!pool) {
    createSiloedKey(tableName, key, plansTable, jwt, rand, callback);
  } else {
    createPooledKey(pool, tableName, key, jwt, callback);
  }
}

The getPoolForPlanId() function does a search for a pool of keys associated with the usage plan. If there is a pool, we “create” a kind of reference to the pooled resource, rather than a completely new key that is created by the API Gateway service directly. The lambda/api_key_pools.js should be empty.

exports.apiKeyPools = [];

In effect, all usage plans were considered as siloed keys up to now. To change that, populate the data structure with values from the six API keys that were created manually. You will have to look up the IDs of the API keys and usage plans that were created in API Gateway (Figures 2 and 3). Using the AWS console to navigate to API Gateway is the most intuitive.

A view of the AWS console when inspecting the ID for the Basic usage plan

Figure 2. A view of the AWS console when inspecting the ID for the Basic usage plan

A view of the AWS Console when looking up the API key value (not the ID)

Figure 3. A view of the AWS Console when looking up the API key value (not the ID)

When done, your code in lambda/api_key_pools.js should be the following, but instead of ellipses (…), the IDs for the user plans and API keys specific to your environment will appear.

exports.apiKeyPools = [{
    planName: "FreePlan"
    planId: "...",
    apiKeys: [ "..." ]
  },
 {
    planName: "BasicPlan"
    planId: "...",
    apiKeys: [ "...", "...", "...", "...", "..." ]
  }];

After making the code changes, run cdk deploy from the command line to update the Lambda functions. This change will only affect key creation and deletion because of the system implementation. Updates affect only the user’s specific reference to the key, not the underlying resource managed by API Gateway.

When the web application is run now, it will look similar to before—tenants should not be aware what tiering strategy they have been assigned to. The only way to notice the difference would be to create two Free Tier keys, test them, and note that the value of the X-API-KEY header is unchanged between the two.

Now, you have a virtually unlimited number of users who can have API keys in the Free or Basic Tier. By keeping the Premium Tier siloed, you are subject to the 10,000-API-key maximum (less any keys allocated for the lower tiers). You may consider additional techniques to continue to scale, such as replicating your service in another AWS account.

Other production considerations

The sample code is minimal, and it illustrates just one aspect of scaling a Software-as-a-service (SaaS) application. There are many other aspects be considered in a production setting that we explore in this section.

The throttled endpoint, GET /api rely only on API key for authorization for demonstration purpose. For any production implementation consider authentication options for your REST APIs. You may explore and extend to require authentication with Cognito similar to /admin/* endpoints in the sample code.

One API key for Free Tier access and five API keys for Basic Tier access are illustrative in a sample code but not representative of production deployments. Number of API keys with service quota into consideration, business and technical decisions may be made to minimize noisy neighbor effect such as setting blast radius upper threshold of 0.1% of all users. To satisfy that requirement, each tier would need to spread users across at least 1,000 API keys. The number of keys allocated to Basic or Premium Tier would depend on market needs and pricing strategies. Additional allocations of keys could be held in reserve for troubleshooting, QA, tenant migrations, and key retirement.

In the planning phase of your solution, you will decide how many tiers to provide, how many usage plans are needed, and what throttle limits and quotas to apply. These decisions depend on your architecture and business.

To define API request limits, examine the system API Gateway is protecting and what load it can sustain. For example, if your service will scale up to 1,000 requests per second, it is possible to implement three tiers with a 10/50/40 split: the lowest tier shares one common API key with a 100 request per second limit; an intermediate tier has a pool of 25 API keys with a limit of 20 requests per second each; and the highest tier has a maximum of 10 API keys, each supporting 40 requests per second.

Metrics play a large role in continuously evolving your SaaS-tiering strategy (Figure 4). They provide rich insights into how tenants are using the system. Tenant-aware and SaaS-wide metrics on throttling and quota limits can be used to: assess tiering in-place, if tenants’ requirements are being met, and if currently used tenant usage profiles are valid (Figure 5).
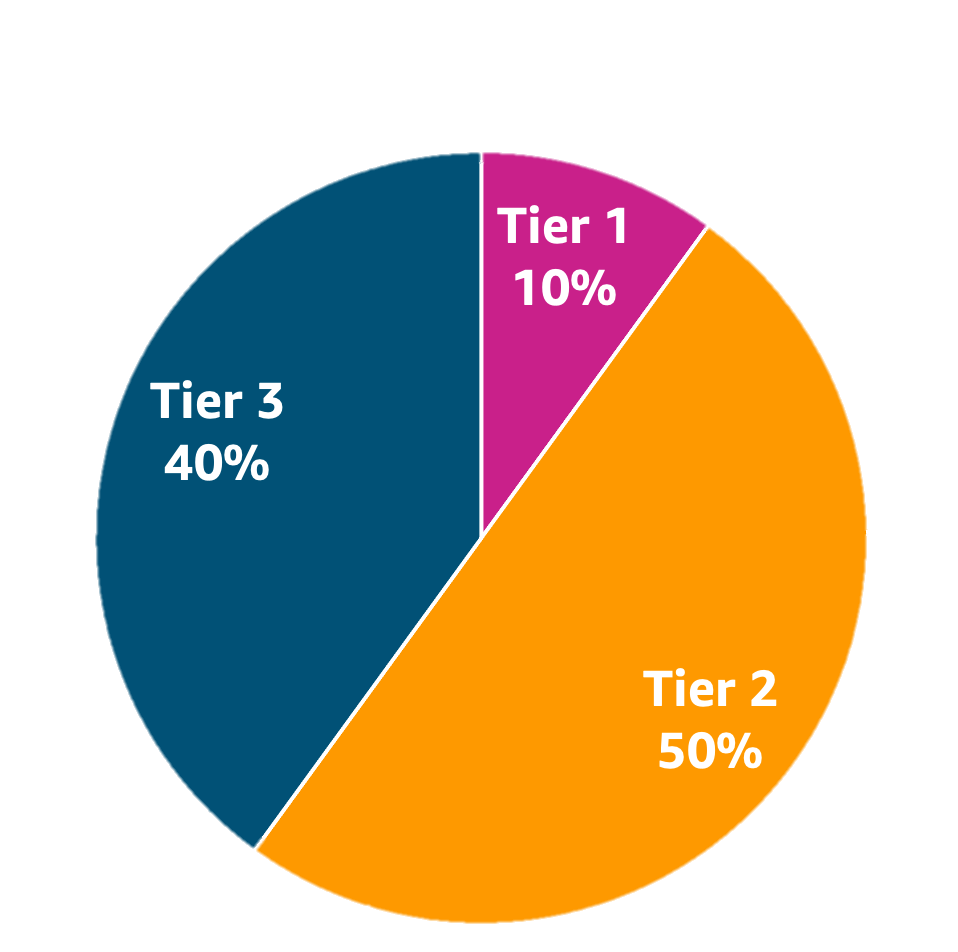
Tiering strategy example with 3 tiers and requests allocation per tier

Figure 4. Tiering strategy example with 3 tiers and requests allocation per tier

An example SaaS metrics dashboard

Figure 5. An example SaaS metrics dashboard

API Gateway provides options for different levels of granularity required, including detailed metrics, and execution and access logging to enable observability of your SaaS solution. Granular usage metrics combined with underlying resource consumption leads to managing optimal experience for your tenants with throttling levels and policies per method and per client.

Cleanup

To avoid incurring future charges, delete the resources. This can be done on the command line by typing:

cd ${TOP}/cdk
cdk destroy

cd ${TOP}/react
amplify delete

${TOP} is the topmost directory of the sample code. For the most up-to-date information, see the README.md file.

Conclusion

In this two-part blog series, we have reviewed the best practices and challenges of effectively guarding a tiered multi-tenant REST API hosted in AWS API Gateway. We also explored how throttling policy and quota management can help you continuously evaluate the needs of your tenants and evolve your tiering strategy to protect your backend systems from being overwhelmed by inbound traffic.

Further reading:

Throttling a tiered, multi-tenant REST API at scale using API Gateway: Part 1

Post Syndicated from Nick Choi original https://aws.amazon.com/blogs/architecture/throttling-a-tiered-multi-tenant-rest-api-at-scale-using-api-gateway-part-1/

Many software-as-a-service (SaaS) providers adopt throttling as a common technique to protect a distributed system from spikes of inbound traffic that might compromise reliability, reduce throughput, or increase operational cost. Multi-tenant SaaS systems have an additional concern of fairness; excessive traffic from one tenant needs to be selectively throttled without impacting the experience of other tenants. This is also known as “the noisy neighbor” problem. AWS itself enforces some combination of throttling and quota limits on nearly all its own service APIs. SaaS providers building on AWS should design and implement throttling strategies in all of their APIs as well.

In this two-part blog series, we will explore tiering and throttling strategies for multi-tenant REST APIs and review tenant isolation models with hands-on sample code. In part 1, we will look at why a tiering and throttling strategy is needed and show how Amazon API Gateway can help by showing sample code. In part 2, we will dive deeper into tenant isolation models as well as considerations for production.

We selected Amazon API Gateway for this architecture since it is a fully managed service that helps developers to create, publish, maintain, monitor, and secure APIs. First, let’s focus on how Amazon API Gateway can be used to throttle REST APIs with fine granularity using Usage Plans and API Keys. Usage Plans define the thresholds beyond which throttling should occur. They also enable quotas, which sets a maximum usage per a day, week, or month. API Keys are identifiers for distinguishing traffic and determining which Usage Plans to apply for each request. We limit the scope of our discussion to REST APIs because other protocols that API Gateway supports — WebSocket APIs and HTTP APIs — have different throttling mechanisms that do not employ Usage Plans or API Keys.

SaaS providers must balance minimizing cost to serve and providing consistent quality of service for all tenants. They also need to ensure one tenant’s activity does not affect the other tenants’ experience. Throttling and quotas are a key aspect of a tiering strategy and important for protecting your service at any scale. In practice, this impact of throttling polices and quota management is continuously monitored and evaluated as the tenant composition and behavior evolve over time.

Architecture Overview

Figure 1. Cloud Architecture of the sample code.

Figure 1 – Architecture of the sample code

To get a firm foundation of the basics of throttling and quotas with API Gateway, we’ve provided sample code in AWS-Samples on GitHub. Not only does it provide a starting point to experiment with Usage Plans and API Keys in the API Gateway, but we will modify this code later to address complexity that happens at scale. The sample code has two main parts: 1) a web frontend and, 2) a serverless backend. The backend is a serverless architecture using Amazon API Gateway, AWS Lambda, Amazon DynamoDB, and Amazon Cognito. As Figure I illustrates, it implements one REST API endpoint, GET /api, that is protected with throttling and quotas. There are additional APIs under the /admin/* resource to provide Read access to Usage Plans, and CRUD operations on API Keys.

All these REST endpoints could be tested with developer tools such as curl or Postman, but we’ve also provided a web application, to help you get started. The web application illustrates how tenants might interact with the SaaS application to browse different tiers of service, purchase API Keys, and test them. The web application is implemented in React and uses AWS Amplify CLI and SDKs.

Prerequisites

To deploy the sample code, you should have the following prerequisites:

For clarity, we’ll use the environment variable, ${TOP}, to indicate the top-most directory in the cloned source code or the top directory in the project when browsing through GitHub.

Detailed instructions on how to install the code are in ${TOP}/INSTALL.md file in the code. After installation, follow the ${TOP}/WALKTHROUGH.md for step-by-step instructions to create a test key with a very small quota limit of 10 requests per day, and use the client to hit that limit. Search for HTTP 429: Too Many Requests as the signal your client has been throttled.

Figure 2: The web application (with browser developer tools enabled) shows that a quick succession of API calls starts returning an HTTP 429 after the quota for the day is exceeded.

Figure 2: The web application (with browser developer tools enabled) shows that a quick succession of API calls starts returning an HTTP 429 after the quota for the day is exceeded.

Responsibilities of the Client to support Throttling

The Client must provide an API Key in the header of the HTTP request, labelled, “X-Api-Key:”. If a resource in API Gateway has throttling enabled and that header is missing or invalid in the request, then API Gateway will reject the request.

Important: API Keys are simple identifiers, not authorization tokens or cryptographic keys. API keys are for throttling and managing quotas for tenants only and not suitable as a security mechanism. There are many ways to properly control access to a REST API in API Gateway, and we refer you to the AWS documentation for more details as that topic is beyond the scope of this post.

Clients should always test for the response to any network call, and implement logic specific to an HTTP 429 response. The correct action is almost always “try again later.” Just how much later, and how many times before giving up, is application dependent. Common approaches include:

  • Retry – With simple retry, client retries the request up to defined maximum retry limit configured
  • Exponential backoff – Exponential backoff uses progressively larger wait time between retries for consecutive errors. As the wait time can become very long quickly, maximum delay and a maximum retry limits should be specified.
  • Jitter – Jitter uses a random amount of delay between retry to prevent large bursts by spreading the request rate.

AWS SDK is an example client-responsibility implementation. Each AWS SDK implements automatic retry logic that uses a combination of retry, exponential backoff, jitter, and maximum retry limit.

SaaS Considerations: Tenant Isolation Strategies at Scale

While the sample code is a good start, the design has an implicit assumption that API Gateway will support as many API Keys as we have number of tenants. In fact, API Gateway has a quota on available per region per account. If the sample code’s requirements are to support more than 10,000 tenants (or if tenants are allowed multiple keys), then the sample implementation is not going to scale, and we need to consider more scalable implementation strategies.

This is one instance of a general challenge with SaaS called “tenant isolation strategies.” We highly recommend reviewing this white paper ‘SasS Tenant Isolation Strategies‘. A brief explanation here is that the one-resource-per-customer (or “siloed”) model is just one of many possible strategies to address tenant isolation. While the siloed model may be the easiest to implement and offers strong isolation, it offers no economy of scale, has high management complexity, and will quickly run into limits set by the underlying AWS Services. Other models besides siloed include pooling, and bridged models. Again, we recommend the whitepaper for more details.

Figure 3. Tiered multi-tenant architectures often employ different tenant isolation strategies at different tiers. Our example is specific to API Keys, but the technique generalizes to storage, compute, and other resources.

Figure 3- Tiered multi-tenant architectures often employ different tenant isolation strategies at different tiers. Our example is specific to API Keys, but the technique generalizes to storage, compute, and other resources.

In this example, we implement a range of tenant isolation strategies at different tiers of service. This allows us to protect against “noisy-neighbors” at the highest tier, minimize outlay of limited resources (namely, API-Keys) at the lowest tier, and still provide an effective, bounded “blast radius” of noisy neighbors at the mid-tier.

A concrete development example helps illustrate how this can be implemented. Assume three tiers of service: Free, Basic, and Premium. One could create a single API Key that is a pooled resource among all tenants in the Free Tier. At the other extreme, each Premium customer would get their own unique API Key. They would protect Premium tier tenants from the ‘noisy neighbor’ effect. In the middle, the Basic tenants would be evenly distributed across a set of fixed keys. This is not complete isolation for each tenant, but the impact of any one tenant is contained within “blast radius” defined.

In production, we recommend a more nuanced approach with additional considerations for monitoring and automation to continuously evaluate tiering strategy. We will revisit these topics in greater detail after considering the sample code.

Conclusion

In this post, we have reviewed how to effectively guard a tiered multi-tenant REST API hosted in Amazon API Gateway. We also explored how tiering and throttling strategies can influence tenant isolation models. In Part 2 of this blog series, we will dive deeper into tenant isolation models and gaining insights with metrics.

If you’d like to know more about the topic, the AWS Well-Architected SaaS Lens Performance Efficiency pillar dives deep on tenant tiers and providing differentiated levels of performance to each tier. It also provides best practices and resources to help you design and reduce impact of noisy neighbors your SaaS solution.

To learn more about Serverless SaaS architectures in general, we recommend the AWS Serverless SaaS Workshop and the SaaS Factory Serverless SaaS reference solution that inspired it.

Let’s Architect! Serverless architecture on AWS

Post Syndicated from Luca Mezzalira original https://aws.amazon.com/blogs/architecture/lets-architect-serverless-architecture-on-aws/

Serverless architecture and computing allow you and your teams to focus on delivering business value in place of investing time tweaking the infrastructure characteristics. AWS is not only providing serverless computing as a service, but share that half of our new applications built by Amazon are using AWS Lambda, as noted by Andy Jassy in his 2020 re:Invent keynote.

In this post, we share insights into reimagining a serverless environment.

I Build Applications – Event-driven Architecture

Event-driven architecture is common in modern applications built with microservices, and it is the cornerstone for designing serverless workloads. It uses events to trigger and communicate between decoupled services.

With this video, you can learn how to start with a prototype then scale to mass adoption using decoupled systems that run when responding to, without needing to redesign. Danilo Poccia, Chief Evangelist at AWS, begins the session with the APIs, then gives an example on how to build an event-driven architecture using Amazon EventBridge. The session closes with how to understand what is happening in this exchange of events.

Event-driven communication with asynchronous invocation

Event-driven communication with asynchronous invocation

Building modern cloud applications? Think integration

This re:Invent 2021 session explains modern cloud applications based on serverless or microservices, and how connections between components define important characteristics, like scalability, availability, and coupling.

How your systems are interconnected describes your system’s essential properties, such as resiliency and changeability. Gregor Hohpe, AWS Enterprise Strategist, shares tips on what to consider when integrating different services, such as lifecycle, level of control over the systems you are integrating, and how integration becomes an integral part of your software delivery cycle. The goal is to use the same method to integrate at the same speed as software deployment.

Integration approaches with Gregor Hohpe

Integration approaches with Gregor Hohpe

Serverless architectural patterns and best practices

Serverless architectures require a mindset shift: existing patterns need to be revisited, and new patterns created using the new architecture style. For each pattern created by AWS, we provide operational, security, and reliability best practices and discuss potential challenges. We also demonstrate some patterns in reference architecture diagrams.

This session helps you identify services and applications to create serverless architectures and understand areas of potential savings, increased agility, and reliability in your organization. Heitor Lessa, Principal Solutions Architect at AWS, starts the session identifying the benefits of Lambda Power Tuning: he details setting up memory when there are hundreds of functions, then follows with best practices for the pattern created.

Best practices for serverless architecture

Best practices for serverless architecture

Best practices of advanced serverless developers

This session is an overview of architectural best practices, optimizations, and handy codes that can be used to build secure, scalable, and high-performance serverless applications.

Julian Wood, Senior Developer Advocate at AWS, provides the recommended practices for implementing serverless applications inside your company, such as Lambda, to transform and not transport, avoid monolithic services and functions, orchestrate workflow with step functions, choreograph events. Julian also touches on understanding different ways you can invoke Lambda functions and what you should be aware of with each invocation model.

Three types of AWS Lambda invocation models

Three types of AWS Lambda invocation models

Building next-gen applications with event-driven architectures

Maintaining data consistency across multiple services can be challenging. It can also be difficult to work with large amounts of data in different data stores and locations. Teams building microservices architectures often find that integration with other applications and external services can make their workloads more monolithic and tightly coupled.

In this session, you can learn how to use event-based architectures to decouple and decentralize application components. Coupling is not one-dimensional, and it’s a trade-off to balance and optimize over time. This video demonstrates patterns based on message queues and events: for each pattern you can learn the advantages, the disadvantages, and the options for building it on AWS.

Sam Dengler, Principal Solutions Architect at AWS, explains the mental models to apply while designing choreography and orchestration in a scenario with microservices. The strategy adopted by Taco Bell for identifying their bounded contexts is also detailed, as well as the architecture built on Lambda for running the business logic and on AWS Step Functions for orchestration.

Choreography and orchestration are two modes of interaction in a microservices architecture

Choreography and orchestration are two modes of interaction in a microservices architecture

See you next time!

Thanks for joining our discussion on serverless architecting! If you want to deep dive into the topic, read all about Serverless on AWS!

See you in a couple of weeks when we discuss architecting for resilience!

Looking for more architecture content? AWS Architecture Center provides reference architecture diagrams, vetted architecture solutions, Well-Architected best practices, patterns, icons, and more!

Other posts in this series

Build a custom Java runtime for AWS Lambda

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/compute/build-a-custom-java-runtime-for-aws-lambda/

This post is written by Christian Müller, Principal AWS Solutions Architect and Maximilian Schellhorn, AWS Solutions Architect

When running applications on AWS Lambda, you have the option to use either one of the managed runtime versions that AWS provides or bring your own custom runtime. The following blog post provides a walkthrough of how you can create and optimize a custom runtime for Java based Lambda functions.

Builders might rely on customized or experimental runtime behavior when creating solutions in the cloud. The Java ecosystem fosters innovation and encourages experiments with the current six-month release schedule for the latest runtime versions.

However, Lambda focuses on providing stable long-term support (LTS) versions. The official Lambda runtimes are built around a combination of operating system, programming language, and software libraries that are subject to maintenance and security updates. For example, the Lambda runtime for Java supports the LTS versions Java 8 Corretto and Java 11 Corretto as of April 2022. The Java 17 Corretto version is pending. In addition, there is no provided runtime for non LTS versions like Java 15 Corretto, Java 16 Corretto, or Java 18 Corretto.

To use other language versions, Lambda allows you to create custom runtimes. Custom runtimes allow builders to provide and configure their own runtimes for running their application code. To enable communication between your custom runtime and Lambda, you can use the runtime interface client library in Java.

With the introduction of modular runtime images in Java 9 (JEP 220), it is possible to include only the Java runtime modules that your application depends on. This reduces the overall runtime size and increases performance, especially during cold-starts. In addition, there are other techniques in Java, like class data sharing and tiered compilation, which allow you to reduce the startup time of your application even further.

To combine those capabilities, this blog post provides an overview for creating and deploying a minified Java runtime on Lambda by using Java 18 Corretto. For step-by-step instructions and prerequisites, refer to the official GitHub example.

Overview of the example

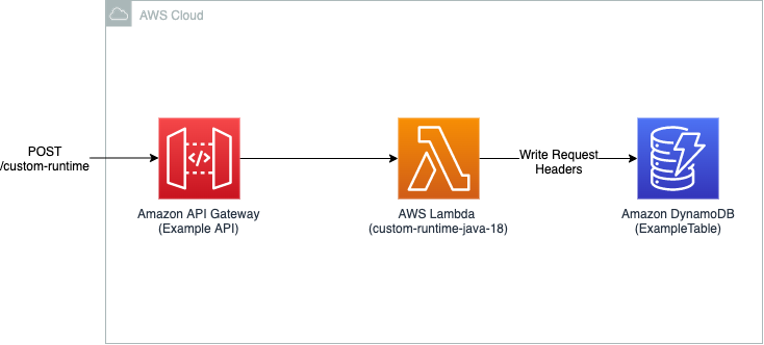
In the following example, you build a custom runtime for a basic Java application that writes request headers to Amazon DynamoDB and is fronted by Amazon API Gateway.

Application architecture

The following diagram summarizes the steps to create the application and the custom runtime:

Steps to create the application custom runtime

  1. Download the preferred Java version and take advantage of jdeps, jlink and class data sharing to create a minified and optimized Java runtime based on the application code (function.jar).
  2. Create a bootstrap file with optimized starting instructions for the application.
  3. Package the application code, the optimized Java runtime, and the bootstrap file as a zip file.
  4. Deploy the runtime, including the app, to Lambda. For example, using the AWS Cloud Development Kit (CDK)

Steps 1–3 are automated and abstracted via Docker. The following section provides a high-level walkthrough of the build and deployment process. For the full version, see the Dockerfile in the GitHub example.

Creating the optimized Java runtime

1. Download the desired Java version and copy the local application code to the Docker environment and build it with Maven:

FROM amazonlinux:2

...

# Update packages and install Amazon Corretto 18, Maven and Zip
RUN yum -y update
RUN yum install -y java-18-amazon-corretto-devel maven zip

...

# Copy the software folder to the image and build the function
COPY software software
WORKDIR /software/example-function
RUN mvn clean package

2. This step results in an uber-jar (function.jar) that you can use as an input argument for jdeps. The output is a file containing all the Java modules that the function depends on:

RUN jdeps -q \
    --ignore-missing-deps \
    --multi-release 18 \
    --print-module-deps \
    target/function.jar > jre-deps.info

3. Create an optimized Java runtime based on those application modules with jlink. Remove unnecessary information from the runtime, for example header files or man-pages:

RUN jlink --verbose \
    --compress 2 \
    --strip-java-debug-attributes \
    --no-header-files \
    --no-man-pages \
    --output /jre18-slim \
    --add-modules $(cat jre-deps.info)

4. This creates your own custom Java 18 runtime in the /jre18-slim folder. You can apply additional optimization techniques such as Class-Data-Sharing (CDS) to generate a classes.jsa file to accelerate the class loading time of the JVM.

RUN /jre18-slim/bin/java -Xshare:dump

Adding optimized starting instructions

You must tell the Lambda execution environment how to start the application. You can achieve that with a bootstrap file that includes the necessary instructions. In addition, you can define parameters to improve the performance further. For example, you could use tiered compilation and SerialGC.

The following snippet represents an example of a bootstrap file:

#!/bin/sh

$LAMBDA_TASK_ROOT/jre18-slim/bin/java \
    --add-opens java.base/java.util=ALL-UNNAMED \
    -XX:+TieredCompilation \
    -XX:TieredStopAtLevel=1 \
    -XX:+UseSerialGC \
    -jar function.jar "$_HANDLER"

Packaging the components

Combine the bootstrap file, the custom Java runtime, and the application code in a zip file for later use as the deployment package:

RUN zip -r runtime.zip \
    bootstrap \
    function.jar \
    /jre18-slim

The GitHub example provides a build.sh script to run the above-mentioned process via Docker. This results in a runtime.zip that you can then use as a deployment package.

Deploying the application with the custom runtime

To deploy the custom runtime, use AWS CDK. This allows you to define the needed infrastructure as code more easily in your favorite programming language.

The following code snippet shows how to create a Lambda function from a custom runtime:

Function customJava18Function = new Function(this, "LambdaCustomRuntimeJava18", FunctionProps.builder()
        .functionName("custom-runtime-java-18")
.handler("com.amazon.aws.example.ExampleDynamoDbHandler::handleRequest")
        .runtime(Runtime.PROVIDED_AL2)
        .code(Code.fromAsset("../runtime.zip"))
        .memorySize(512)
        .environment(Map.of("TABLE_NAME", exampleTable.getTableName()))
        .timeout(Duration.seconds(20))
        .logRetention(RetentionDays.ONE_WEEK)
        .build());

To deploy the application and output the necessary API Gateway URL to invoke the Lambda function, use the following command or use the provided provision_infrastructure.sh script:

cdk deploy --outputs-file target/outputs.json

Testing the application and validating the example results

After deployment, you can load test the application with the open-source software project Artillery.

The following command creates 120 concurrent invocations of the Lambda function for a duration of 60 seconds. It uses the API Gateway URL that is exported after the AWS CDK successfully deployed the application:

artillery run -t $(cat infrastructure/target/outputs.json | jq -r '.LambdaCustomRuntimeMinimalJRE18InfrastructureStack.apiendpoint') -v '{ "url": "/custom-runtime" }' infrastructure/loadtest.yml

Use CloudWatch Log Insights to query the Lambda logs and gather information about the cold start (initDuration) and duration percentiles:

filter @type = "REPORT"
    | parse @log /\d+:\/aws\/lambda\/(?<function>.*)/
    | stats
    count(*) as invocations,
    pct(@duration+coalesce(@initDuration,0), 0) as p0,
    pct(@duration+coalesce(@initDuration,0), 25) as p25,
    pct(@duration+coalesce(@initDuration,0), 50) as p50,
    pct(@duration+coalesce(@initDuration,0), 75) as p75,
    pct(@duration+coalesce(@initDuration,0), 90) as p90,
    pct(@duration+coalesce(@initDuration,0), 95) as p95,
    pct(@duration+coalesce(@initDuration,0), 99) as p99,
    pct(@duration+coalesce(@initDuration,0), 100) as p100
    group by function, ispresent(@initDuration) as coldstart
    | sort by coldstart, function

The results provide an indication of how your application performs with the custom runtime. This is especially helpful when comparing different versions.

  • Invocation time (@duration) for both cold and warm starts plus function initialization time (@initDuration) if it is a cold start:

Invocation time

  • Function initialization time (@initDuration) only:

Function initialisation time

Conclusion

In this blog post, you learn how to create your own optimized Java runtime for AWS Lambda by using a variety of Java optimization techniques. This allows you to tailor your Java runtime to your application needs.

See the full example on GitHub and make use of your own preferred Java version. Add additional optimization steps in the Dockerfile or tune the parameters in the bootstrap file to optimize the start of the Java virtual machine.

In case you want to re-use your custom runtime in multiple Lambda functions, you can also distribute it via a Lambda layer.

For more serverless learning resources, visit Serverless Land.

Let’s Architect! Using open-source technologies on AWS

Post Syndicated from Luca Mezzalira original https://aws.amazon.com/blogs/architecture/lets-architect-using-open-source-technologies-on-aws/

With open-source technology, authors make software available to the public, who can view, use, or change it and add new features or support new capabilities. Open-source technology promotes collaboration across different teams, organizations, and people because the process often includes different perspectives and ideas, which typically results a stronger solution.

It can be difficult to create a multi-use solution when building to solve for a specific challenge. With an open-source project or an initiative, multiple teams work together, which prevents coupling and makes the solution easier to generalize.

In this edition of Let’s Architect!, we show you some open-source technologies built with AWS and options for running well-known, open-source projects on AWS.

Firecracker: Secure and Fast microVMs for Serverless Computing

Firecracker was developed at AWS to improve the customer experience of services like AWS Lambda and AWS Fargate. This technology is used to deploy workloads in lightweight virtual machines (VMs), called microVMs. For example, when a new Lambda function is triggered in response to an event, AWS Lambda provisions a microVM (if none already exists) to handle the request. Behind the scenes, this is powered by Firecracker.

This video introduces Firecracker and the concept of virtual machine monitor as a technology to create and manage microVMs. This talk explains Firecracker’s foundation, the minimal device model, and how it interacts with various containers. You’ll learn about the performance, security, and utilization improvements enabled by Firecracker and how Firecracker is used for Lambda and Fargate.

An example host running Firecracker microVMs

An example host running Firecracker microVMs

Deep dive into AWS Cloud Development Kit

AWS Cloud Development Kit (CDK) is an open-source software development framework that allows you to define your cloud application resources using familiar programming languages. It uses object-oriented design to create resources and build an end-to-end process for application development from infrastructure and software-development perspectives.

This video introduces AWS CDK core concepts and demonstrates how to create custom resources and deploy them to the cloud. With AWS CDK, you can make deployments repeatable, automate operations through infrastructure as code, and use the software design patterns while coding your architecture.

AWS CDK is an open-source software development framework for defining cloud infrastructure as code

AWS CDK is an open-source software development framework for defining cloud infrastructure as code

Using Apollo Server on AWS Lambda with Amazon EventBridge for real-time, event-driven streaming

Apollo Server is an open-source, spec-compliant GraphQL server that’s compatible with any GraphQL client. This blog posts covers how you can architect Apollo Server on AWS Lambda in an event-driven architecture. It shows you how to use the Apollo Server on AWS Lambda, integrate it with REST and WebSocket APIs and communicate asynchronously via event bus.

Sample application: a chat app that receives a text message from the client and responds with French and German translations of the message

Sample application: a chat app that receives a text message from the client and responds with French and German translations of the message

Observability the open-source way

Removing the undifferentiated heavy lifting for implementing open-source software can allow you to plug-and-play your favorite solutions with existing AWS services. This video addresses best practices and real-world use cases for Amazon Managed Service for Prometheus, Amazon Managed Grafana, and AWS Distro for OpenTelemetry to gain observability. Observability is fundamental to collect and analyze data coming from your architecture, understand the status of your system, and take action to improve application performance.

Setting up Amazon Managed Service for Prometheus

Setting up Amazon Managed Service for Prometheus

See you next time!

See you in a couple of weeks when we discuss strategies for running serverless applications on AWS!

Looking for more architecture content? AWS Architecture Center provides reference architecture diagrams, vetted architecture solutions, Well-Architected best practices, patterns, icons, and more!

Other posts in this series

Handling Lambda functions idempotency with AWS Lambda Powertools

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/handling-lambda-functions-idempotency-with-aws-lambda-powertools/

This post is written by Jerome Van Der Linden, Solutions Architect Builder and Dariusz Osiennik, Sr Cloud Application Architect.

One of the advantages of using AWS Lambda is its integration with messaging services like Amazon SQS or Amazon EventBridge. The integration is managed and can also handle the retrying of failed messages. If there’s an error within the Lambda function, the failed message is sent again and the function is re-invoked.

This feature increases the resilience of the application but also means that a message can be processed multiple times by the function. This is important when managing orders, payments, or any kind of transaction that must be handled only once.

As mentioned in the design principles of Lambda, “since the same event may be received more than once, functions should be designed to be idempotent”. This article explains what idempotency is and how to implement it more easily with Lambda Powertools.

Understanding idempotency

Idempotency is the property of an operation whereby it can be applied multiple times without changing the result beyond the initial application. You can run an idempotent operation safely multiple times without any side effects like duplicates or inconsistent data. For example, this is a key principle for infrastructure as code, where you don’t want to double the number of resources each time you apply a template.

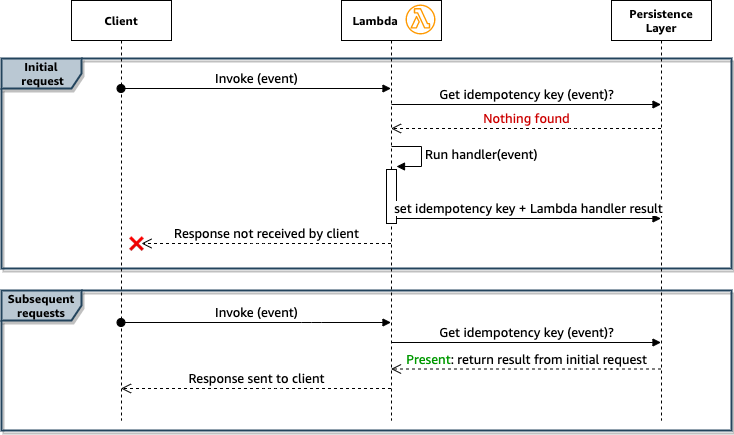
Applied to Lambda, a function is idempotent when it can be invoked multiple times with the same event with no risk of side effects. To make a function idempotent, it must first identify that an event has already been processed. Therefore, it must extract a unique identifier, called an “idempotency key”.

This identifier may be in the event payload (for example, orderId), a combination of multiple fields in the payload (for example, customerId, and orderId), or even a hash of the full payload. If using the full payload, fields such as dates, timestamps, or random elements may affect the hash and lead to changing values.

The function then checks in a persistence layer (for example, Amazon DynamoDB or Amazon ElastiCache):

  • If the key is not there, then the Lambda function can proceed normally, perform the transaction, and save the idempotency key in the persistence layer. You can potentially add the result of the function in the persistence layer too, so that subsequent calls can retrieve this result directly.
  • If the key is there, then the function can return and avoid applying the transaction again.

The following diagram shows the sequence of events with this idempotency scenario:

Sequence diagram

There are edge cases in this example:

  • You can invoke the function twice with the same event within a few milliseconds. In that case, each function acts as if it’s the first time this event is received and processes it, resulting in inconsistencies.
  • The function may perform several operations that are not idempotent. If the first operation is successful and then an error happens, the idempotency key won’t be saved. Subsequent calls redo the first operation, resulting in inconsistencies.

You can guard against these edge cases by inserting a lock as soon as the event is received:

Second sequence diagram

There are other questions and edge cases that you must consider when implementing idempotency on your Lambda functions. Read Making retries safe with idempotent APIs from the Builder’s Library to dive into the details. You can choose to implement idempotency by yourself or you can use a library that handles it and takes care of these edge cases for you. This is what Lambda Powertools (for Python and Java) proposes.

Idempotency with Lambda Powertools

Lambda Powertools is a library, available in Python, Java, and TypeScript. It provides utilities for Lambda functions to ease the adoption of best practices and to reduce the amount of code to perform recurring tasks. In particular, it provides a module to handle idempotency (in the Java and Python versions).

This post shows examples using the Java version. To get started with the Lambda Powertools idempotency module, you must install the library and configure it within your build process. For more details, follow AWS Lambda Powertools documentation.

Next, you must configure a persistence storage layer where the idempotency feature can store its state. You can use the built-in support for DynamoDB or you can create your own implementation for the database of your choice. This example creates a new table in DynamoDB.

The following AWS Serverless Application Model (AWS SAM) template creates a suitable table to store the state:

Resources:
  IdempotencyTable:
    Type: AWS::DynamoDB::Table
    Properties:
      AttributeDefinitions:
        - AttributeName: id
          AttributeType: S
      KeySchema:
        - AttributeName: id
          KeyType: HASH
      TimeToLiveSpecification:
        AttributeName: expiration
        Enabled: true
      BillingMode: PAY_PER_REQUEST

In this definition:

  • The table is multi-tenant and can be reused by multiple Lambda functions that use the Powertools idempotency module.
  • The DynamoDB time-to-live configuration helps keep idempotency limited in time. You can configure the duration, which is 1 hour by default.

Configure the idempotency module’s behavior in the init phase of the function’s lifecycle, before the handleRequest method gets called:

public class SubscriptionHandler implements RequestHandler<Subscription, SubscriptionResult> {

  public SubscriptionHandler() {
    Idempotency.config().withPersistenceStore(
      DynamoDBPersistenceStore.builder()
        .withTableName(System.getenv("TABLE_NAME"))
        .build()
      ).configure();
  }
}

Lambda Powertools follows the paradigm of convention over configuration and provides default values for many parameters. The persistence store is the only required element. To use the DynamoDB implementation, you must specify a table name. In the previous sample, the name is provided by the environment variable TABLE_NAME.

Adding the @Idempotent annotation to the handleRequest method enables the idempotency functionality. It uses a hash of the Subscription event as the idempotency key.

@Idempotent
  public SubscriptionResult handleRequest(final Subscription event, final Context context) {
    SubscriptionPayment payment = createSubscriptionPayment(
      event.getUsername(),
      event.getProductId()
    );

    return new SubscriptionResult(payment.getId(), "success", 200);
  }

Creating orders

The example is about creating an order for a user for a list of products. Orders should not be duplicated if the client repeats the request. API consumers can safely retry a create order request in case of issues (such as a timeout or networking disruption). The application should also allow the user to buy the same products in a short period of time if that is the user’s intention.

The following architecture diagram consists of an Amazon API Gateway REST API, the idempotent Lambda function, and a DynamoDB table for storing orders.

Architecture diagram

The Orders API allows creating a new order by calling its POST /orders endpoint with the following sample payload:

{
  "requestToken": "260d2efe-af84-11ec-b909-0242ac120002",
  "userId": "user1",  
  "items": [
    {
      "productId": "product1",      
      "price": 6.50,      
      "quantity": 5    
    },    
    {
      "productId": "product2",      
      "price": 13.50,      
      "quantity": 2    
    }
  ],  
  "comment": "AWSome Order"
}

Lambda Powertools uses JMESPath to extract the important fields from the request that uniquely identify it. It then calculates a hash of these fields to constitute the idempotency key.

In the example, the important fields are the userId and the items, to avoid duplicated orders. But the user can also buy the same list of products in a short period of time. To allow this, the API consumer can generate a client-side token and assign its value to the requestToken field. For each unique order, the token has a different value. If a request is retried by the client, it uses the same token.

This leads to the following configuration for the idempotency key:

Idempotency.config()
  .withConfig( 
    IdempotencyConfig.builder()
    .withEventKeyJMESPath("powertools_json(body).[requestToken,userId,items]")
    .build())

If the same request is sent more than once, only the first call results in a new order created in the DynamoDB table. The same order identifier is returned by the endpoint for all the subsequent calls. In this way, the API consumer can safely retry the requests without worrying about duplicating the order.

You can find the source code of the example on GitHub.

Processing payments

This example shows asynchronous batch processing of payment messages from a queue. Messages must not be processed more than once to avoid charging users multiple times for the same order. You must consider edge cases like at-least-once message delivery, an error response returned by the third party payment API or retrying the batch of messages.

The following architecture diagram shows an Amazon SQS queue, the idempotent Lambda function, and a third-party API that the function calls for payment.

Architecture diagram

This is the body of a single payment SQS message:

{
    "orderId": "order1",
    "userId": "user1",
    "amount": "50.25"
}

In this example, the process method is annotated as idempotent, not the handleRequest. The method is responsible for processing a single payment record from the SQS batch. It uses @IdempotencyKey annotation to specify which parameter to use as the idempotency key.

@Override
public List<String> handleRequest(SQSEvent sqsEvent, Context context) {
return sqsEvent.getRecords()
  .stream()
  .map(record -> process(record.getMessageId(),record.getBody()))
  .collect(Collectors.toList());
}

@Idempotent
private String process(String messageId, @IdempotencyKey String messageBody) {
    logger.info("Processing messageId: {}", messageId);
    PaymentRequest request = 
extractDataFrom(messageBody).as(PaymentRequest.class);
    return paymentService.process(request);
}

If an SQS record with the same payload is received more than once, the third-party API is not called multiple times. All the subsequent calls return before calling the process method.

If an exception is thrown from the process method, the idempotency feature does not store the idempotency state in the persistence layer. The payment is treated as unprocessed and can be retried safely. This may happen if the third-party API returns a server-side error.

By default, if one message from a batch fails, all the messages in the batch are retried. Lambda Powertools also offers the SQS Batch Processing module which can help in handling partial failures.

You can find the source code of this example in the GitHub repo.

Conclusion

Idempotency is a critical piece of serverless architectures and can be difficult to implement. If not done correctly, it can lead to inconsistent data and other issues. This post shows how you can use Lambda Powertools to make Lambda functions idempotent and ensure that critical transactions are handled only once.

For more details about the Lambda Powertools idempotency feature and its configuration options, refer to the full documentation.

For more serverless learning resources, visit Serverless Land.

How MarketAxess® uses AWS Developer Tools to create scalable and secure CI/CD pipelines

Post Syndicated from Aaron Lima original https://aws.amazon.com/blogs/devops/how-marketaxess-uses-aws-developer-tools-to-create-scalable-and-secure-ci-cd-pipelines/

Very often,  enterprise organizations strive to adopt modern DevOps practices, tofocus on governance and security without sacrificing development velocity. In this guest post, Prashant Joshi, Senior Cloud Engineer at MarketAxess, explains how they use the AWS Cloud Development Kit (AWS CDK), AWS CodePipeline, and AWS CodeBuild to simplify the developer experience by dynamically provisioning pipelines and maintaining governance at MarketAxess.

Problem Statement

MarketAxess is a financial technology company that operates an e-trading platform, for institutional credit markets. As MarketAxess adopted DevOps firm-wide, we struggled to ensure pipeline consistency. We had developers using static code analysis and linting, but it wasn’t enforced. As more teams began to adopt DevOps practices, the importance of providing consistency over code quality, security scanning, and artifact management grew. However, we were challenged with increasing our engineering workforce and implementing best practices in the various pipelines. As a small team, we needed a way to reliably manage and scale pipelines while reducing engineering overhead. We thought about the DevOps tenets, as well as the importance of automation, and we decided to build automation that would provision pipelines for development teams.  These pipelines included best practices for Continuous Integration and Continuous Deployment (CI/CD). We wanted to build this automation with self-service, so that teams can get started developing a solution to a business problem, without having to spend too much time around the CI/CD aspects of their projects.

We chose the AWS CDK to deploy AWS CodePipeline, AWS CodeBuild, and AWS Identity and Access Management (IAM) resources, and used an API webhook using AWS Lambda and Amazon API Gateway for integration. In this post, we provide an example of how these services can be used to create dynamic cross account CI/CD pipelines.

Solution

In developing our solution, we wanted to accomplish three main goals:

  1. Standardization and Governance of Pipelines – We wanted to ensure consistent practices in each team’s pipeline to make sure of code quality and security.
  2. Simplified Developer Interaction – We wanted developers to focus mainly on interacting with the code repository for their project.
  3. Improve Management of Dynamically Provisioned Pipelines – Knowing that we would need to make changes, improvements, and enhancements, we wanted tools and a process that was flexible.

We achieved these goals using AWS CDK to automate the creation of CodePipeline and define mandatory actions in the pipeline. We also created a webhook using API Gateway to integrate with our Bitbucket repositories to automatically trigger the automation. The pipelines can dynamically be provisioned or updated based on the YAML manifest file submitted to the repository. We process the manifest file with Amazon Elastic Container Service (Amazon ECS) Fargate tasks, because we had containerized the processing components using Docker. However, with the release of container support in Lambda, we are now considering this as a potential replacement. These pipelines run CI stages based on the programing language defined by development teams in the manifest file, and they deploy a tested versioned artifact to the corresponding environments via standard Software Defined Lifecycle (SDLC) practices. As a part of CI stages, we semantically version our code and tag our commits accordingly. This lets us trace commit to pipeline execution. The following architecture diagram shows a CloudFormation pipeline generated via AWS CDK.

CloudFormation Pipeline Architecture Diagram

The process flow is as follows:

  1. Developer pushes a change to the repository.
  2. A webhook is triggered when the Pull Request is merged that creates or modifies the pipeline based on the manifest file submitted to the repository.
  3. This triggers a Lambda function that performs the following:
    1. Clones the repository from Internally hosted BitBucket repos.
    2. Uploads the repository to the source Amazon Simple Storage Service (Amazon S3) bucket, which is encrypted using Customer Managed Keys (CMK) with the AWS Key Management Service (KMS).
    3. An ECS Task is run, and a manifest file is passed which gives the project parameters. Pipelines are built according to these project parameters.
  4. An ECS Task processes the metadata file and runs cdk Logic, finally it triggers the pipeline.
    1. As source code is progressed through the pipeline, the build stage output to the artifact bucket. Pipeline artifacts are encrypted with a CMK. The IAM roles in the target account only have access to this bucket.

Additionally, through the power of the IAM integration with CodePipeline, the team could implement session tags with IAM roles and Okta to make sure that independent teams only approve pipelines, which are owned by respective teams. Furthermore, we use attribute-based tags to protect the production environment from unauthorized actions, so that deployment to production can only come through the pipeline.

The AWS CDK-based pipelines let MarketAxess enable teams to independently build and obtain immediate feedback, while still centrally governing CI and CD patterns. The solution took six months of two DevOps engineers working full time to build the cdk structure and support for the core languages and their corresponding CI and CD stages. We continue to iterate on the cdk code base and pipelines, incorporating feedback from our development community to ensure developer satisfaction.

Simplified Developer Interaction

Although we were enforcing standards via the automation, we still wanted to give development teams autonomy through a simple mechanism. We wanted developers to interact with our pipeline creation process through a pipeline manifest file that they submitted to their repository. An example of the manifest file schema is in the following screenshot:

Manifest File Schema

As shown above, the manifest lets developers define custom application configurations, while preserving consistent quality gates. This manifest is checked in to source control, and upon a commit to the code repository it triggers our automation. This lets our pipelines mutate on manifest file changes, and it makes sure that the latest commit goes through the latest quality gates. Each repository gets its own pipeline, and, to maintain the security of the pipeline, we used IAM Session Tags with Okta. We tag each pipeline and its associated resources with a unique attribute that is mapped to the development team so that they only have access to their pipelines, and only authorized individuals may approve production deployments.

Using AWS CDK, AWS CodePipeline, and other AWS Services, we have been able to improve the stability and quality of the code being delivered. CodePipeline and AWS CDK have helped us develop a cloud native pipeline solution that meets our governance best practices and compliance requirements. We met our three goals, and we can iterate and change easily moving forward.

Conclusion

Organizations that achieve the automation and self-service ideals of DevOps can build, release, and deploy features and apps to users faster and at higher levels of quality. In this post, we saw a real-life example of using Infrastructure as Code with AWS CDK to build a service that helps maintain governance and helps developers get work done. Here are two other posts that demonstrate using AWS Service Catalog to create secure DevOps pipelines or DevOps pipelines that deploy containerized applications.


Prashant Joshi

Prashant Joshi

Prashant Joshi is a Senior Cloud Engineer working in the Cloud Foundation team at MarketAxess. MarketAxess is a registered trademark of MarketAxess Holdings Inc.

Building a serverless cloud-native EDI solution with AWS

Post Syndicated from Ripunjaya Pattnaik original https://aws.amazon.com/blogs/architecture/building-a-serverless-cloud-native-edi-solution-with-aws/

Electronic data interchange (EDI) is a technology that exchanges information between organizations in a structured digital form based on regulated message formats and standards. EDI has been used in healthcare for decades on the payer side for determination of coverage and benefits verification. There are different standards for exchanging electronic business documents, like American National Standards Institute X12 (ANSI), Electronic Data Interchange for Administration, Commerce and Transport (EDIFACT), and Health Level 7 (HL7).

HL7 is the standard to exchange messages between enterprise applications, like a Patient Administration System and a Pathology Laboratory Information. However, HL7 messages are embedded in Health Insurance Portability and Accountability Act (HIPAA) X12 for transactions between enterprises, like hospital and insurance companies.

HIPAA is a federal law that required the creation of national standards to protect sensitive patient health information from being disclosed without the patient’s consent or knowledge. It also mandates healthcare organizations to follow a standardized mechanism of EDI to submit and process insurance claims.

In this blog post, we will discuss how you can build a serverless cloud-native EDI implementation on AWS using the Edifecs XEngine Server.

EDI implementation challenges

Due to its structured format, EDI facilitates the consistency of business information for all participants in the exchange process. The primary EDI software that is used processes the information and then translates it into a more readable format. This can be imported directly and automatically into your integration systems. Figure 1 shows a high-level transaction for a healthcare EDI process.

EDI Transaction Sets exchanges between healthcare provider and payer

Figure 1. EDI Transaction Sets exchanges between healthcare provider and payer

Along with the implementation itself, the following are some of the common challenges encountered in EDI system development:

  1. Scaling. Despite the standard protocols of EDI, the document types and business rules differ across healthcare providers. You must scale the scope of your EDI judiciously to handle a diverse set of data rules with multiple EDI protocols.
  2. Flexibility in EDI integration. As standards evolve, your EDI system development must reflect those changes.
  3. Data volumes and handling bad data. As the volume of data increases, so does the chance for errors. Your storage plans must adjust as well.
  4. Agility. In healthcare, EDI handles business documents promptly, as real-time document delivery is critical.
  5. Compliance. State Medicaid and Medicare rules and compliance can be difficult to manage. HIPAA compliance and CAQH CORE certifications can be difficult to acquire.

Solution overview and architecture data flow

Providers and Payers can send requests as enrollment inquiry, certification request, or claim encounter to one another. This architecture uses these as source data requests coming from the Providers and Payers as flat files (.txt and .csv), Active Message Queues, and API calls (submitters).

The steps for the solution shown in Figure 2 are as follows:

1. Flat, on-premises files are transferred to Amazon Simple Storage Service (S3) buckets using AWS Transfer Family (2).
3. AWS Fargate on Amazon Elastics Container Service (Amazon ECS) runs Python packages to convert the transactions into JSON messages, then queues it on Amazon MQ (4).
5. Java Message Service (JMS) Bridge, which runs Apache Camel on Fargate, pulls the messages from the on-premises messaging systems and queues them on Amazon MQ (6).
7. Fargate also runs programs to call the on-premises API or web services to get the transactions and queues it on Amazon MQ (8).
9. Amazon CloudWatch monitors the queue depth. If queue depth goes beyond a set threshold, CloudWatch sends notifications to the containers through Amazon Simple Notification Service (SNS) (10).
11. Amazon SNS triggers AWS Lambda, which adds tasks to Fargate (12), horizontally scaling it to handle the spike.
13. Fargate runs Python programs to read the messages on Amazon MQ and uses PYX12 packages to convert the JSON messages to EDI file formats, depending on the type of transactions.
14. The container also may queue the EDI requests on different queues, as the solution uses multiple trading partners for these requests.
15. The solution runs Edifecs XEngine Server on Fargate with Docker image. This polls the messages from the queues previously mentioned and converts them to EDI specification by the trading partners that are registered with Edifecs.
16. Python module running on Fargate converts the response from the trading partners to JSON.
17. Fargate sends JSON payload as a POST request using Amazon API Gateway, which updates requestors’ backend systems/databases (12) that are running microservices on Amazon ECS (11).
18. The solution also runs Elastic Load Balancing to balance the load across the Amazon ECS cluster to take care of any spikes.
19. Amazon ECS runs microservices that uses Amazon RDS (20) for domain specific data.

EDI transaction-processing system architecture on AWS

Figure 2. EDI transaction-processing system architecture on AWS

Handling PII/PHI data

The EDI request and response file includes protected health information (PHI)/personal identifiable information (PII) data related to members, claims, and financial transactions. The solution leverages all AWS services that are HIPAA eligible and encrypts data at rest and in-transit. The file transfers are through FTP, and the on-premises request/response files are Pretty Good Privacy (PGP) encrypted. The Amazon S3 buckets are secured through bucket access policies and are AES-256 encrypted.

Amazon ECS tasks that are hosted in Fargate use ephemeral storage that is encrypted with AES-256 encryption, using an encryption key managed by Fargate. User data stored in Amazon MQ is encrypted at rest. Amazon MQ encryption at rest provides enhanced security by encrypting data using encryption keys stored in the AWS Key Management Service. All connections between Amazon MQ brokers use Transport Layer Security to provide encryption in transit. All APIs are accessed through API gateways secured through Amazon Cognito. Only authorized users can access the application.

The architecture provides many benefits to EDI processing:

  • Scalability. Because the solution is highly scalable, it can speed integration of new partner/provider requirements.
  • Compliance. Use the architecture to run sensitive, HIPAA-regulated workloads. If you plan to include PHI (as defined by HIPAA) on AWS services, first accept the AWS Business Associate Addendum (AWS BAA). You can review, accept, and check the status of your AWS BAA through a self-service portal available in AWS Artifact. Any AWS service can be used with a healthcare application, but only services covered by the AWS BAA can be used to store, process, and transmit protected health information under HIPAA.
  • Cost effective. Though serverless cost is calculated by usage, with this architecture you save as your traffic grows.
  • Visibility. Visualize and understand the flow of your EDI processing using Amazon CloudWatch to monitor your databases, queues, and operation portals.
  • Ownership. Gain ownership of your EDI and custom or standard rules for rapid change management and partner onboarding.

Conclusion

In this healthcare use case, we demonstrated how a combination of AWS services can be used to increase efficiency and reduce cost. This architecture provides a scalable, reliable, and secure foundation to develop your EDI solution, while using dependent applications. We established how to simplify complex tasks in order to manage and scale your infrastructure for a high volume of data. Finally, the solution provides for monitoring your workflow, services, and alerts.

For further reading:

Announcing AWS Lambda Function URLs: Built-in HTTPS Endpoints for Single-Function Microservices

Post Syndicated from Alex Casalboni original https://aws.amazon.com/blogs/aws/announcing-aws-lambda-function-urls-built-in-https-endpoints-for-single-function-microservices/

Organizations are adopting microservices architectures to build resilient and scalable applications using AWS Lambda. These applications are composed of multiple serverless functions that implement the business logic. Each function is mapped to API endpoints, methods, and resources using services such as Amazon API Gateway and Application Load Balancer.

But sometimes all you need is a simple way to configure an HTTPS endpoint in front of your function without having to learn, configure, and operate additional services besides Lambda. For example, you might need to implement a webhook handler or a simple form validator that runs within an individual Lambda function.

Today, I’m happy to announce the general availability of Lambda Function URLs, a new feature that lets you add HTTPS endpoints to any Lambda function and optionally configure Cross-Origin Resource Sharing (CORS) headers.

This lets you focus on what matters while we take care of configuring and monitoring a highly available, scalable, and secure HTTPS service.

How Lambda Function URLs Work
Create a new function URL and map it to any function. Each function URL is globally unique and can be associated with a function’s alias or the function’s unqualified ARN, which implicitly invokes the $LATEST version.

For example, if you map a function URL to your $LATEST version, each code update will be available immediately via the function URL. On the other hand, I’d recommend mapping a function URL to an alias, so you can safely deploy new versions, perform some integration tests, and then update the alias when you’re ready. This also lets you implement weighted traffic shifting and safe deployments.

Function URLs are natively supported by the Lambda API, and you can start using it via the AWS Management Console or AWS SDKs, as well as infrastructure as code(IaC) tools such as AWS CloudFormation, AWS SAM, or AWS Cloud Development Kit (AWS CDK).

Lambda Function URLs in Action
You can configure a function URL for a new or an existing function. Let’s see how to implement a new function to handle a webhook.

When creating a new function, I check Enable function URL in Advanced Settings.

Here, I select Auth type: AWS_IAM or NONE. My webhook will use custom authorization logic based on a signature provided in the HTTP headers. Therefore, I’ll choose AuthType None, which means Lambda won’t check for any AWS IAM Sigv4 signatures before invoking my function. Instead, I’ll extract and validate a custom header in my function handler for authorization.

AWS Lambda URLs - Create Function

Please note that when using AuthType None, my function’s resource-based policy must still explicitly allow for public access. Otherwise, unauthenticated requests will be rejected. You can add permissions programmatically using the AddPermission API. In this case, the Lambda console automatically adds the necessary policy for me, as the IAM role I’m using is authorized to call the AddPermission API in my account.

With one click, I can also enable CORS. The default CORS configuration will allow all origins. Then, I’ll add more granular controls after creating the function. In case you’re not familiar with CORS, it’s a header-based security mechanism implemented by browsers to make sure that only certain hosts are allowed to load resources and invoke APIs. If a website is allowed to consume your API, you’ll need to include a few CORS headers that declare which origins, methods, and custom headers are allowed. The new function URLs take care of it for you, so you don’t have to implement all of this in your Lambda handler.

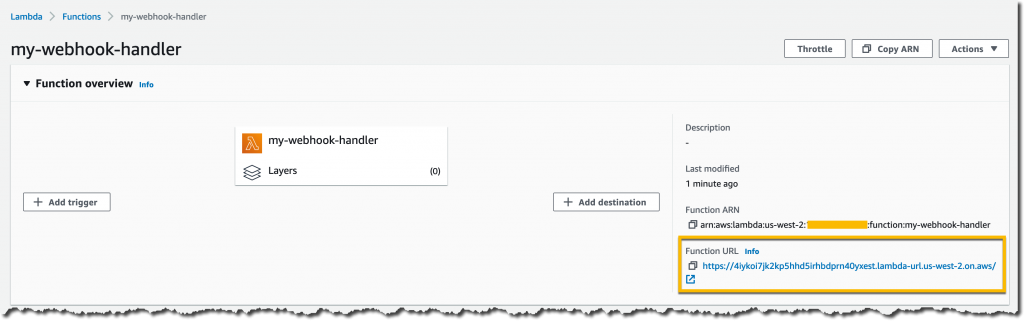
A few seconds later, the function URL is available. I can also easily find and copy it in the Lambda console.

AWS Lambda URLs - Console URL

The function code that handles my webhook in Node.js looks like this:

exports.handler = async (event) => {
    
    // (optional) fetch method and querystring
    const method = event.requestContext.http.method;
    const queryParam = event.queryStringParameters.myCustomParameter;
    console.log(`Received ${method} request with ${queryParam}`)
    
    // retrieve signature and payload
    const webhookSignature = event.headers.SignatureHeader;
    const webhookPayload = JSON.parse(event.body);
    
    try {
        validateSignature(webhookSignature); // throws if invalid signature
        handleEvent(webhookPayload); // throws if processing error
    } catch (error) {
        console.error(error)
        return {
            statusCode: 400,
            body: `Cannot process event: ${error}`,
        }
    }

    return {
        statusCode: 200, // default value
        body: JSON.stringify({
            received: true,
        }),
    };
};

The code is extracting a few parameters from the request headers, query string, and body. If you’re already familiar with the event structure provided by API Gateway or Application Load Balancer, this should look very familiar.

After updating the code, I decide to test the function URL with an HTTP client.

For example, here’s how I’d do it with curl:

$ curl "https://4iykoi7jk2kp5hhd5irhbdprn40yxest.lambda-url.us-west-2.on.aws/?myCustomParameter=squirrel"
    -X POST
    -H "SignatureHeader: XYZ"
    -H "Content-type: application/json"
    -d '{"type": "payment-succeeded"}'

Or with a Python script:

import json
import requests

url = "https://4iykoi7jk2kp5hhd5irhbdprn40yxest.lambda-url.us-west-2.on.aws/"
headers = {'SignatureHeader': 'XYZ', 'Content-type': 'application/json'}
payload = json.dumps({'type': 'payment-succeeded'})
querystring = {'myCustomParameter': 'squirrel'}

r = requests.post(url=url, params=querystring, data=payload, headers=headers)
print(r.json())

Don’t forget to set the request’s Content-type to application/json or text/* in your tests, otherwise, the body will be base64-encoded by default, and you’ll need to decode it in the Lambda handler.

Of course, in this case we’re talking about a webhook, so this function will receive requests directly from the external system that I’m integrating with. I only need to provide them with the public function URL and start receiving events.

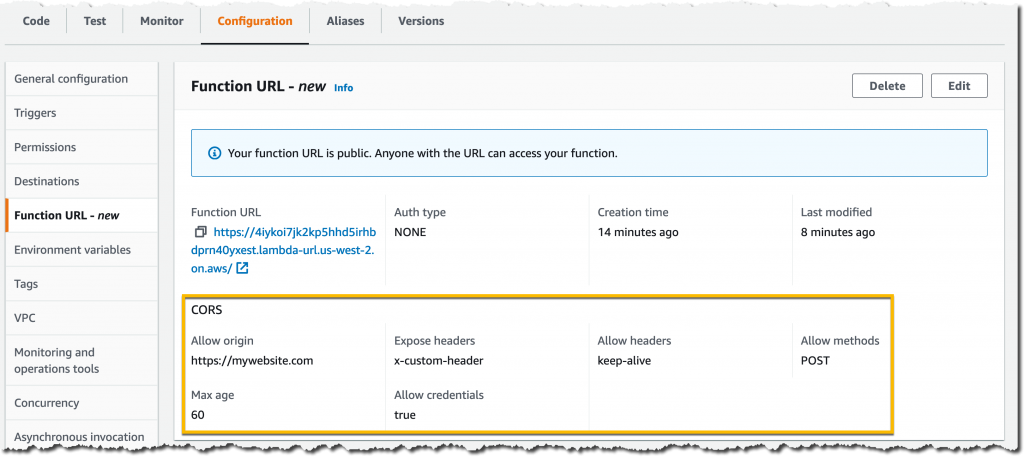
For this specific use case, I don’t need any CORS configuration. In other cases where the function URL is called from the browser, I’d need to configure a few more CORS parameters such as Access-Control-Allow-Origin, Access-Control-Allow-Methods, and Access-Control-Expose-Headers. I can easily review and edit these CORS parameters in the Lambda console or in my IaC templates. Here’s what it looks like in the console:

AWS Lambda URLs - CORS

Also, keep in mind that each function URL is unique and mapped to a specific alias or the $LATEST version of your function. This lets you define multiple URLs for the same function. For example, you can define one for testing the $LATEST version during development and one for each stage or alias, such as staging, production, and so on.

Support for Infrastructure as Code (IaC)
You can start configuring Lambda Function URLs directly in your IaC templates today using AWS CloudFormation, AWS SAM, and AWS Cloud Development Kit (AWS CDK).

For example, here’s how to define a Lambda function and its public URL with AWS SAM, including the alias mapping:

WebhookFunction:
    Type: AWS::Serverless::Function
    Properties:
      CodeUri: webhook/
      Handler: index.handler
      Runtime: nodejs14.x
      AutoPublishAlias: live
      FunctionUrlConfig:
        AuthType: NONE
        Cors:
            AllowOrigins:
                - "https://example.com"

If you have existing Lambda functions in your IaC templates, you can define a new function URL with a few lines of code.

Function URL Pricing
Function URLs are included in Lambda’s request and duration pricing. For example, let’s imagine that you deploy a single Lambda function with 128 MB of memory and an average invocation time of 50 ms. The function receives five million requests every month, so the cost will be $1.00 for the requests, and $0.53 for the duration. The grand total is $1.53 per month, in the US East (N. Virginia) Region.

When to use Function URLs vs. Amazon API Gateway
Function URLs are best for use cases where you must implement a single-function microservice with a public endpoint that doesn’t require the advanced functionality of API Gateway, such as request validation, throttling, custom authorizers, custom domain names, usage plans, or caching. For example, when you are implementing webhook handlers, form validators, mobile payment processing, advertisement placement, machine learning inference, and so on. It is also the simplest way to invoke your Lambda functions during research and development without leaving the Lambda console or integrating additional services.

Amazon API Gateway is a fully managed service that makes it easy for you to create, publish, maintain, monitor, and secure APIs at any scale. Use API Gateway to take advantage of capabilities like JWT/custom authorizers, request/response validation and transformation, usage plans, built-in AWS WAF support, and so on.

Generally Available Today
Function URLs are generally available today in all AWS Regions where Lambda is available, except for the AWS China Regions. Support is also available through many AWS Lambda Partners such as Datadog, Lumigo, Pulumi, Serverless Framework, Thundra, and Dynatrace.

I’m looking forward to hearing how you’re using this new functionality to simplify your serverless architectures, especially in single-function use cases where you want to keep things simple and cost-optimized.

Check out the new Lambda Function URLs documentation.

— Alex

ICYMI: Serverless Q1 2022

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/icymi-serverless-q1-2022/

Welcome to the 16th edition of the AWS Serverless ICYMI (in case you missed it) quarterly recap. Every quarter, we share all the most recent product launches, feature enhancements, blog posts, webinars, Twitch live streams, and other interesting things that you might have missed!

Calendar

In case you missed our last ICYMI, check out what happened last quarter here.

AWS Lambda

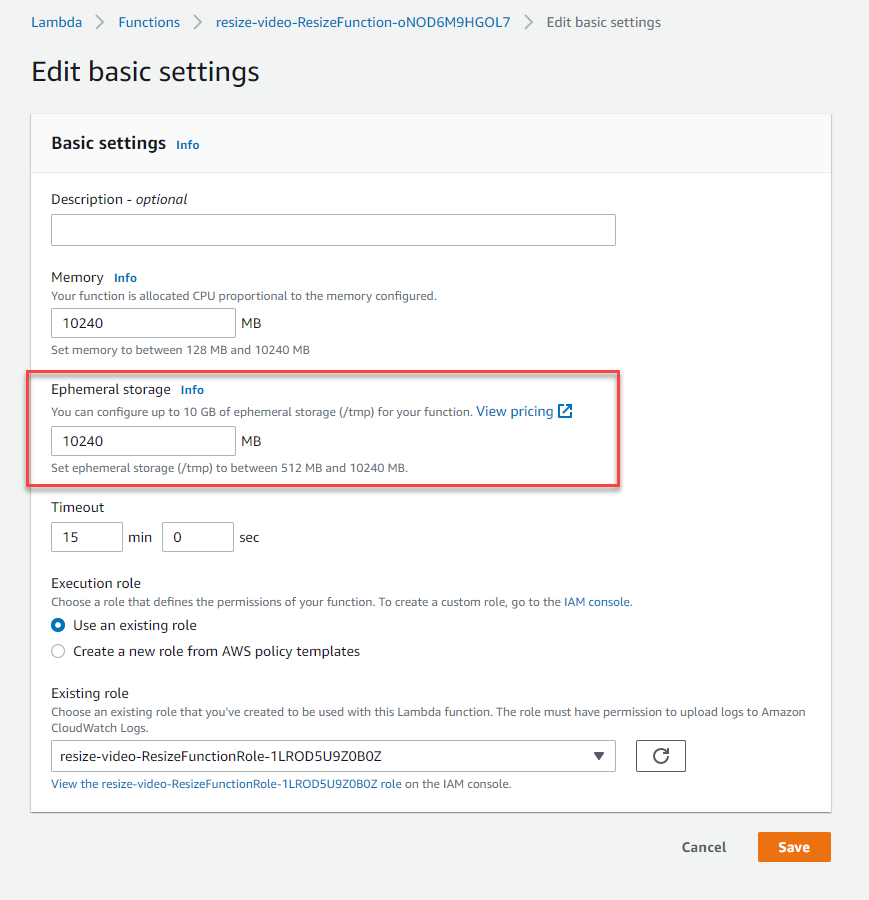
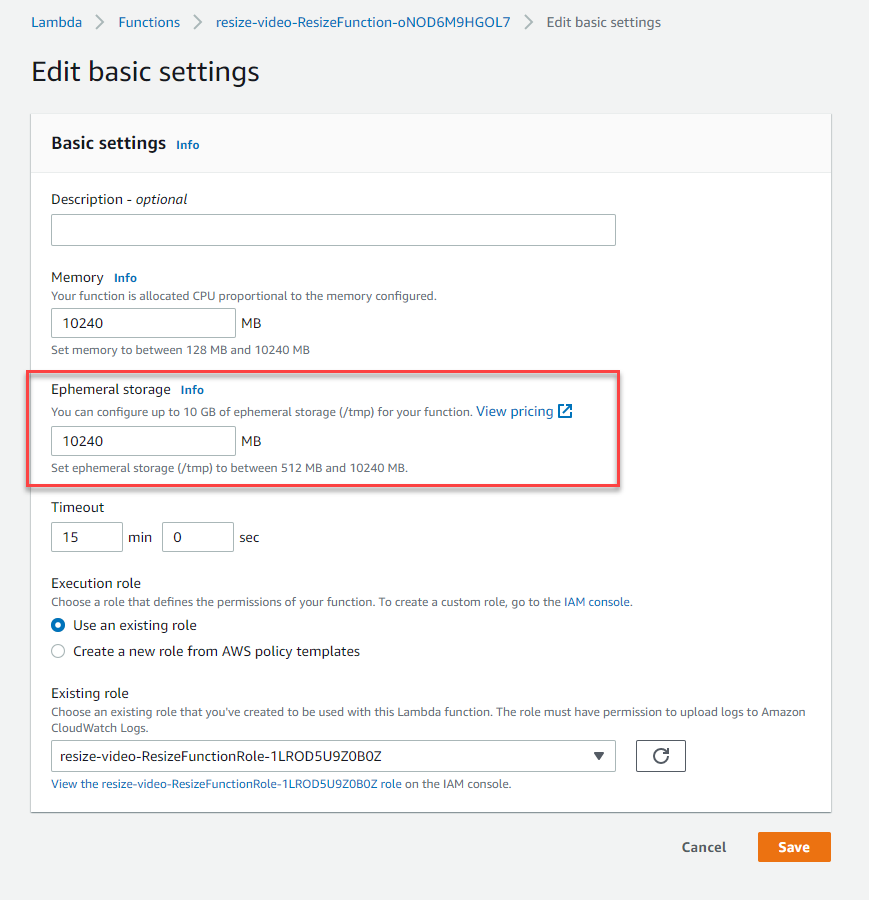
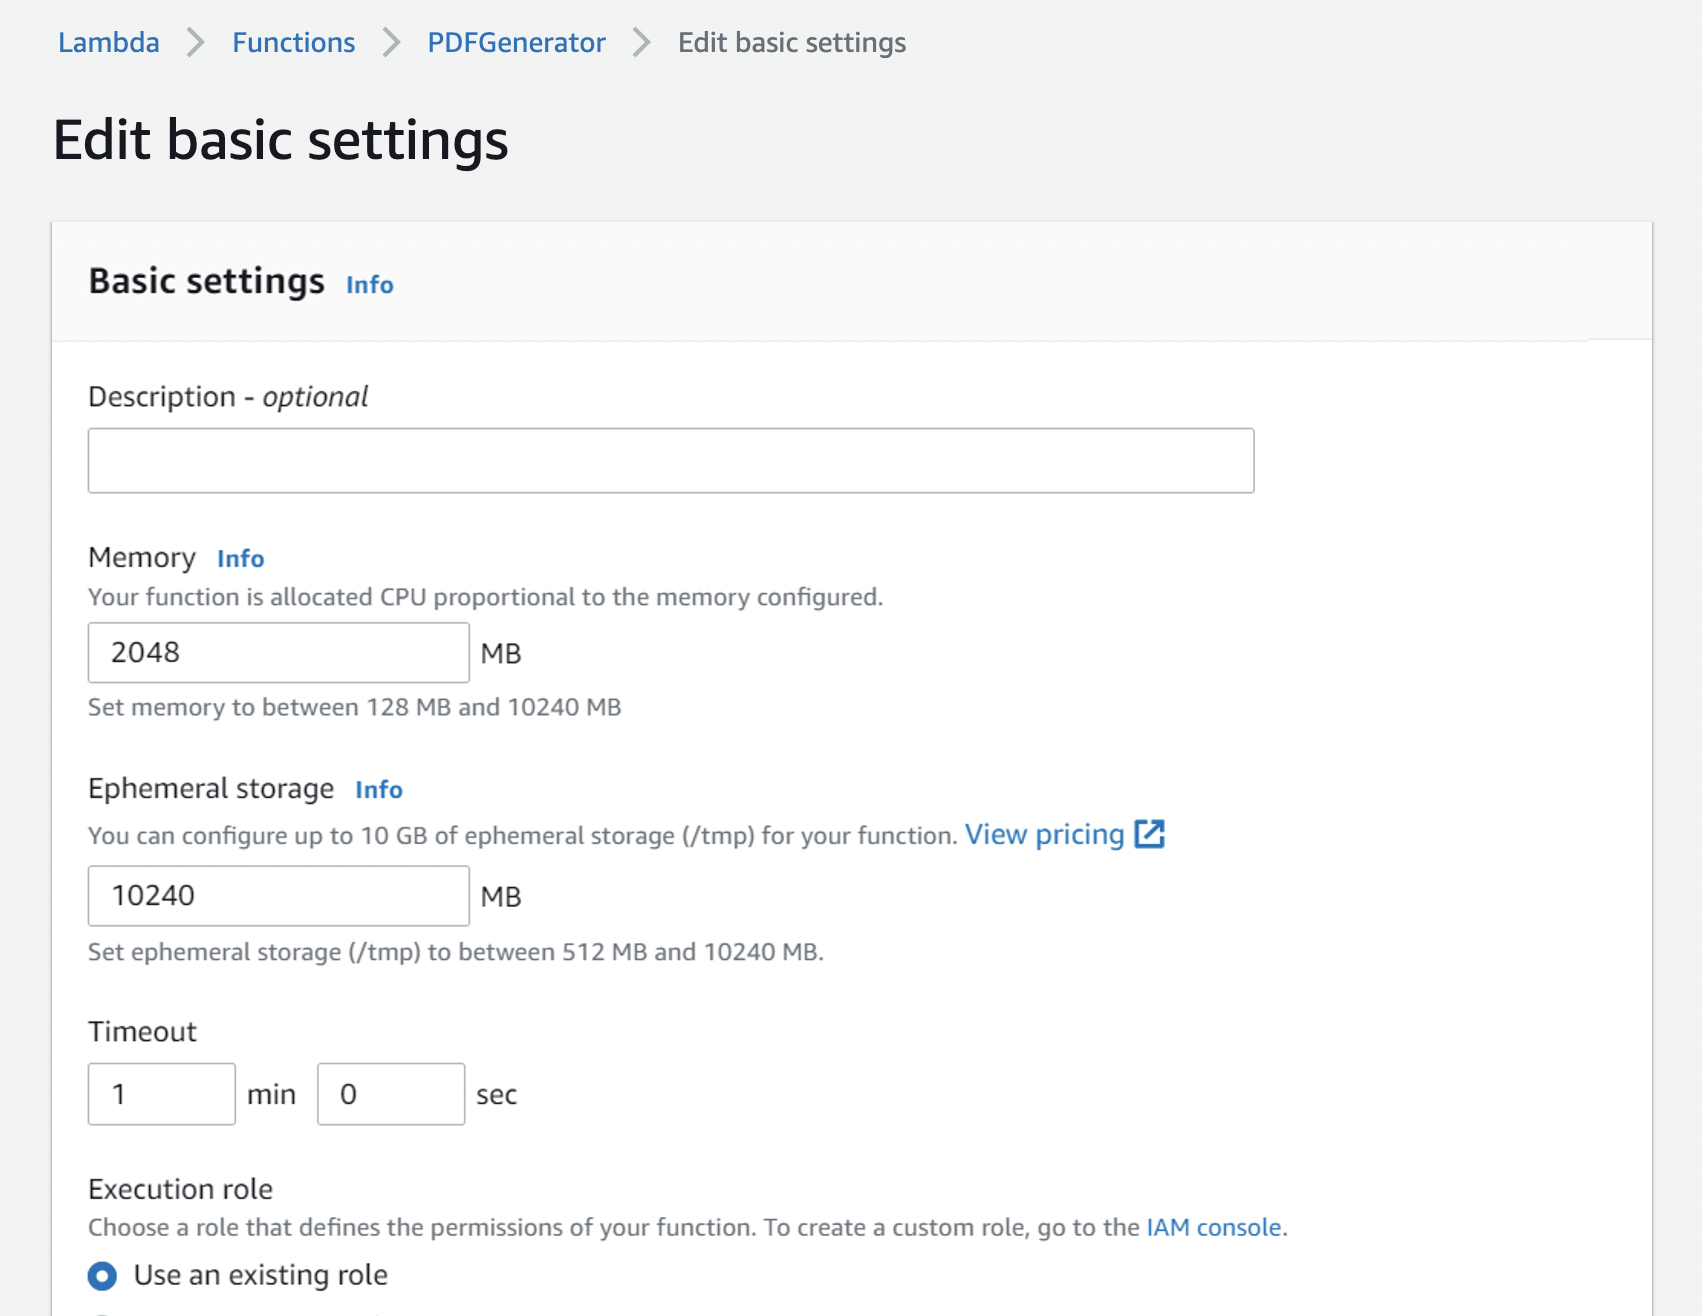
Lambda now offers larger ephemeral storage for functions, up to 10 GB. Previously, the storage was set to 512 MB. There are several common use-cases that can benefit from expanded temporary storage, including extract-transform load (ETL) jobs, machine learning inference, and data processing workloads. To see how to configure the amount of /tmp storage in AWS SAM, deploy this Serverless Land Pattern.

Ephemeral storage settings

For Node.js developers, Lambda now supports ES Modules and top-level await for Node.js 14. This enables developers to use a wider range of JavaScript packages in functions. With top-level await, when used with Provisioned Concurrency, this can improve cold-start performance when using asynchronous initialization.

For .NET developers, Lambda now supports .NET 6 as both a managed runtime and container base image. You can now use new features of the runtime such as improved logging, simplified function definitions using top-level statements, and improved performance using source generators.

The Lambda console now allows you to share test events with other developers in your team, using granular IAM permissions. Previously, test events were only visible to the builder who created them. To learn about creating sharable test events, read this documentation.

Amazon EventBridge

Amazon EventBridge Schema Registry helps you create code bindings from event schemas for use directly in your preferred IDE. You can generate these code bindings for a schema by using the EventBridge console, APIs, or AWS SDK toolkits for Jetbrains (Intellij, PyCharm, Webstorm, Rider) and VS Code. This feature now supports Go, in addition to Java, Python, and TypeScript, and is available at no additional cost.

AWS Step Functions

Developers can test state machines locally using Step Functions Local, and the service recently announced mocked service integrations for local testing. This allows you to define sample output from AWS service integrations and combine them into test cases to validate workflow control. This new feature introduces a robust way to state machines in isolation.

Amazon DynamoDB

Amazon DynamoDB now supports limiting the number of items processed in PartiQL operation, using an optional parameter on each request. The service also increased default Service Quotas, which can help simplify the use of large numbers of tables. The per-account, per-Region quota increased from 256 to 2,500 tables.

AWS AppSync

AWS AppSync added support for custom response headers, allowing you to define additional headers to send to clients in response to an API call. You can now use the new resolver utility $util.http.addResponseHeaders() to configure additional headers in the response for a GraphQL API operation.

Serverless blog posts

January

Jan 6 – Using Node.js ES modules and top-level await in AWS Lambda

Jan 6 – Validating addresses with AWS Lambda and the Amazon Location Service

Jan 20 – Introducing AWS Lambda batching controls for message broker services

Jan 24 – Migrating AWS Lambda functions to Arm-based AWS Graviton2 processors

Jan 31 – Using the circuit breaker pattern with AWS Step Functions and Amazon DynamoDB

Jan 31 – Mocking service integrations with AWS Step Functions Local

February

Feb 8 – Capturing client events using Amazon API Gateway and Amazon EventBridge

Feb 10 – Introducing AWS Virtual Waiting Room

Feb 14 – Building custom connectors using the Amazon AppFlow Custom Connector SDK

Feb 22 – Building TypeScript projects with AWS SAM CLI

Feb 24 – Introducing the .NET 6 runtime for AWS Lambda

March

Mar 6 – Migrating a monolithic .NET REST API to AWS Lambda

Mar 7 – Decoding protobuf messages using AWS Lambda

Mar 8 – Building a serverless image catalog with AWS Step Functions Workflow Studio

Mar 9 – Composing AWS Step Functions to abstract polling of asynchronous services

Mar 10 – Building serverless multi-Region WebSocket APIs

Mar 15 – Using organization IDs as principals in Lambda resource policies

Mar 16 – Implementing mutual TLS for Java-based AWS Lambda functions

Mar 21 – Running cross-account workflows with AWS Step Functions and Amazon API Gateway

Mar 22 – Sending events to Amazon EventBridge from AWS Organizations accounts

Mar 23 – Choosing the right solution for AWS Lambda external parameters

Mar 28 – Using larger ephemeral storage for AWS Lambda

Mar 29 – Using AWS Step Functions and Amazon DynamoDB for business rules orchestration

Mar 31 – Optimizing AWS Lambda function performance for Java

First anniversary of Serverless Land Patterns

Serverless Patterns Collection

The DA team launched the Serverless Patterns Collection in March 2021 as a repository of serverless examples that demonstrate integrating two or more AWS services. Each pattern uses an infrastructure as code (IaC) framework to automate the deployment. These can simplify the creation and configuration of the services used in your applications.

The Serverless Patterns Collection is both an educational resource to help developers understand how to join different services, and an aid for developers that are getting started with building serverless applications.

The collection has just celebrated its first anniversary. It now contains 239 patterns for CDK, AWS SAM, Serverless Framework, and Terraform, covering 30 AWS services. We have expanded example runtimes to include .NET, Java, Rust, Python, Node.js and TypeScript. We’ve served tens of thousands of developers in the first year and we’re just getting started.

Many thanks to our contributors and community. You can also contribute your own patterns.

Videos

YouTube: youtube.com/serverlessland

Serverless Office Hours – Tues 10 AM PT

Weekly live virtual office hours. In each session we talk about a specific topic or technology related to serverless and open it up to helping you with your real serverless challenges and issues. Ask us anything you want about serverless technologies and applications.

YouTube: youtube.com/serverlessland
Twitch: twitch.tv/aws

January

February

March

FooBar Serverless YouTube channel

The Developer Advocate team is delighted to welcome Marcia Villalba onboard. Marcia was an AWS Serverless Hero before joining AWS over two years ago, and she has created one of the most popular serverless YouTube channels. You can view all of Marcia’s videos at https://www.youtube.com/c/FooBar_codes.

January

February

March

AWS Summits

AWS Global Summits are free events that bring the cloud computing community together to connect, collaborate, and learn about AWS. This year, we have restarted in-person Summits at major cities around the world.

The next 4 Summits planned are Paris (April 12), San Francisco (April 20-21), London (April 27), and Madrid (May 4-5). To find and register for your nearest AWS Summit, visit the AWS Summits homepage.

Still looking for more?

The Serverless landing page has more information. The Lambda resources page contains case studies, webinars, whitepapers, customer stories, reference architectures, and even more Getting Started tutorials.

You can also follow the Serverless Developer Advocacy team on Twitter to see the latest news, follow conversations, and interact with the team.

Optimizing AWS Lambda function performance for Java

Post Syndicated from Benjamin Smith original https://aws.amazon.com/blogs/compute/optimizing-aws-lambda-function-performance-for-java/

This post is written by Mark Sailes, Senior Specialist Solutions Architect.

This blog post shows how to optimize the performance of AWS Lambda functions written in Java, without altering any of the function code. It shows how Java virtual machine (JVM) settings affect the startup time and performance. You also learn how you can benchmark your applications to test these changes.

When a Lambda function is invoked for the first time, or when Lambda is horizontally scaling to handle additional requests, an execution environment is created. The first phase in the execution environment’s lifecycle is initialization (Init).

For Java managed runtimes, a new JVM is started and your application code is loaded. This is called a cold start. Subsequent requests then reuse this execution environment. This means that the Init phase does not need to run again. The JVM will already be started. This is called a warm start.

In latency-sensitive applications such as customer facing APIs, it’s important to reduce latency where possible to give the best possible experience. Cold starts can increase the latency for APIs when they occur.

How can you improve cold start latency?

Changing the tiered compilation level can help you to reduce cold start latency. By setting the tiered compilation level to 1, the JVM uses the C1 compiler. This compiler quickly produces optimized native code but it does not generate any profiling data and never uses the C2 compiler.

Tiered compilation is a feature of the Java virtual machine (JVM). It allows the JVM to make best use of both of the just-in-time (JIT) compilers. The C1 compiler is optimized for fast start-up time. The C2 compiler is optimized for the best overall performance but uses more memory and takes a longer time to achieve it.

There are five different levels of tiered compilation. Level 0 is where Java byte code is interpreted. Level 4 is where the C2 compiler analyses profiling data collected during application startup. It observes code usage over a period of time to find the best optimizations. Choosing the correct level can help you optimize your performance.

Changing the tiered compilation level to 1 can reduce cold start times by up to 60%. Thanks to changes in the Lambda execution environment, you can do this in one step with an environment variable for all Java managed runtimes.

Language-specific environment variables

Lambda supports the customization of the Java runtime via language-specific environment variables. The environment variable JAVA_TOOL_OPTIONS allows you to specify additional command line arguments to be used when Java is launched. Using this environment variable, you can change various aspects of the JVM configuration including garbage collection functionality, memory settings as well as the configuration for tiered compilation. To change the tiered compilation level to 1 you would set the value of JAVA_TOOL_OPTIONS to “-XXx:+TieredCompilation -XX:TieredStopAtLevel=1”. When the Java managed runtime starts any value set will be included in the program arguments. For more information on how you can collect and analyses garbage collection data read our Field Notes: Monitoring the Java Virtual Machine Garbage Collection on AWS Lambda.

Customer facing APIs

The following diagram is an example architecture that might be used to create a customer-facing API. Amazon API Gateway is used to manage a REST API and is integrated with Lambda to handle requests. The Lambda function reads and writes data to Amazon DynamoDB to serve the requests.

This is an example use case, which would benefit from optimization. The shorter the duration of each request made to the API the better the customer experience will be.

You can explore the code for this example in the GitHub repo: https://github.com/aws-samples/aws-lambda-java-tiered-compilation-example. The project includes the Lambda function source code, infrastructure as code template, and instructions to deploy it to your own AWS account.

Measuring cold starts

Before you add the environment variable to your Lambda function, measure the current duration for a request. One way to do this is by using the test functionality in the Lambda console.

The following screenshot is a summary from a test invoke, run from the console. You can see that it is a cold start because it includes an Init duration value. If the summary doesn’t include an Init duration, it is a warm start. In this case, the duration is 5,313ms.

Applying the optimization

This change can be configured using AWS Serverless Application Model (AWS SAM), AWS Cloud Development Kit (CDK), AWS CloudFormation, or from within the AWS Management Console.

Using the AWS Management Console:

  1. Navigate to the AWS Lambda console.
  2. Choose Functions and choose the Lambda function to update.
  3. From the menu, choose the Configuration tab and Environment variables. Choose Edit.
  4. Choose Add environment variable. Add the following:
    – Key: JAVA_TOOL_OPTIONS
    – Value: -XXx:+TieredCompilation -XX:TieredStopAtLevel=1

  5. Choose Save. You can verify that the changes are applied by invoking the function and viewing the log events in Amazon CloudWatch. The log line Picked up _JAVA_OPTIONS: -XX:+TieredCompilation -XX:TieredStopAtLevel=1 is added by the JVM during startup.

Checking if performance has improved

Invoke the Lambda function again to see if performance has improved.

The following screenshot shows the results of a test for a function with tiered compilation set to level 1. The duration is 2,169 ms. The cold start duration has decreased by 3,144 ms (59%).

Other use cases

This optimization can be applied to other use cases. Examples could include image resizing, document generation and near real-time ETL pipelines. The common trait being that they do a small number of discrete pieces of work in each execution.

The function code doesn’t have as many candidates for further optimization with the C2 compiler. Even if the C2 compiler did make further optimizations there wouldn’t be enough usage of those optimizations to decrease the total execution time. Instead of allowing this extra compilation to happen, you can tell the JVM not to use the C2 compiler and only use C1.

This optimization may not be suitable if a Lambda function is running for minutes or is repeating the same piece of code thousands of times within the same execution. Frequently executed sections of code are called hot spots, and are prime candidate for further optimization with the C2 compiler.

The C2 compiler analyses profiling data collected as the application runs, and produce a more efficient way to execute that piece of code. After the optimization by the C2 compiler that section of code would execute quicker. Because it is repeated thousands of times in a single Lambda invocation, the overhead of the optimization is worth it overall. An example use case where this would happen is in Monte Carlo simulations. Simulations of random events are calculated thousands, millions, or even billions of times to analyze the most likely outcomes.

Conclusion

In this post, you learn how to improve Lambda cold start performance by up to 60% for functions running the Java runtime. Thanks to the recent changes in the Java execution environment, you can implement these optimizations by adding a single environment variable.

This optimization is suitable for Java workloads such as customer-facing APIs, just-in-time image resizing, near real-time data processing pipelines, and other short-running processes. For more information on tired compilation, read about Tiered Compilation in JVM.

For more serverless learning resources, visit Serverless Land.

Build a multi-language notification system with Amazon Translate and Amazon Pinpoint

Post Syndicated from Praveen Allam original https://aws.amazon.com/blogs/architecture/build-a-multi-language-notification-system-with-amazon-translate-and-amazon-pinpoint/

Organizations with global operations can struggle to notify their customers of any business-related announcements or notifications in different languages. Their customers want to receive notifications in their local language and communication preference. Organizations often rely on complicated third-party services or individuals to manually translate the notifications. This can lead to a loss of revenue due to delayed communication and additional operational expenses.

This blog post demonstrates how to build a straightforward, cost-effective, and scalable multi-language notification system using AWS Serverless technologies. You can post a business-related announcement or notification in English, and based on the customer profile data, it will convert this announcement or notification into different languages. Additionally, the system will also deliver these translated announcements or notifications as an email, voice, or SMS.

Example of a multi-language notification use case

A restaurant franchise company is adding a new item to their menu and plans to release it in North America, Germany, and France. The corporate office has decided to send the following notification.

The company is adding a new item to the menu, and this will go live by May 10. Please ensure you are prepared for this change and plan accordingly.

The franchise owners in Germany want to receive the notifications in the German language, whereas the franchise owners in France want to receive it in French. North American franchises want to receive it in English.

Solution design for multi-language notification system

The solution in Figure 1 demonstrates how to build a multi-language notification system using Amazon Translate and Amazon Pinpoint.

AWS Serverless technologies handle automatic scaling, have built-in high availability architecture, and a pay-for-use billing model, which increases agility and optimizes costs. The system built with this solution is invoked using REST API endpoints. Once this solution is deployed, it can be integrated with any frontend application where users can log in and send out notification events.

Figure 1 illustrates the architecture of this solution.

Solution architecture for multi-language notification system. It includes all the AWS services that are required in this solution. The flow is described as follows.

Figure 1. Solution architecture for multi-language notification system

1. The restaurant franchise will log in to their UI to type the notification message in English. Upon submission, the notification message is sent to the Amazon API Gateway REST endpoint.
Note: In this solution, there is no UI available. You will use a terminal to submit the message.

2. Amazon API Gateway will send this message to Amazon Simple Queue Service (SQS), which will keep the HTTP requests asynchronous.

3. The SQS queue will invoke the SQS AWS Lambda function.

4. The SQS Lambda function invokes the AWS Step Functions state machine. This SQS Lambda function is used as a proxy mechanism to start the state machine workflow. AWS Step Functions are used to orchestrate the notification workflow process. The workflow process validates the message, converts it into different languages, and notifies the customers in their preferred way of communication (email, voice, or SMS). It also handles errors if any of the steps fail by using SQS dead-letter queue.

5. The message entered must be validated in order to ensure that the organizational standards are followed. To perform the message validation, we use the Amazon Comprehend service. Comprehend’s Sentiment analysis will determine whether to send or flag the message. All flagged messages are sent for review.

  • In the example use case message preceding, the message sentiment neutral score is 0.85 confidence. If you set the acceptable score to anything greater than 0.5 confidence, then it is a valid message. Once it passes the validation step, the workflow will proceed to the next step.
  • If the message is vague or not clear, the sentiment score might be less than 0.5 confidence. For example, if this is the message used: We are adding a dish; be ready for it, the sentiment score might be only 0.45 confidence. This is under the acceptable score, and the message will not be processed further.

6. After the message is successfully validated, the message is translated into various languages depending on the customers’ profiles. The Translate Lambda function determines the number of unique languages by referring to the customer profile data in the Amazon DynamoDB table. The function then uses Amazon Translate to translate the message to the different languages required for that notification event. In our example use case, the converted messages will look as follows:

  • German (de):

Das Unternehmen fügt dem Menü einen neuen Punkt hinzu, der bis zum 10. Mai live geschaltet wird. Bitte stellen Sie sicher, dass Sie auf diese Änderung vorbereitet sind und planen Sie entsprechend.

  • French (fr):

La société ajoute un nouvel article au menu, qui sera mis en ligne d’ici le 10 mai. Assurez-vous d’être prêt pour ce changement et de planifier en conséquence.

7. The last step in the workflow is to build the notification logic and deliver the notifications. The Amazon Pinpoint Lambda function retrieves the customer’s profile from the Amazon DynamoDB table. It then parses each record for a given notification event to find out the delivery mode (email, voice, or SMS message). The function then builds the notification logic using Amazon Pinpoint. Amazon Pinpoint notifies each customer either by email, voice, or SMS.

Code repository

The code for this solution is available on GitHub. Review the README file for detailed instructions on how to download and run the solution in your AWS account.

Conclusion

Organizations that operate on an international basis often struggle to build a multi-language notification system to communicate any business-related announcements or notifications to their customers in different languages. Communicating these announcements or notifications in a variety of formats such as email, voice, and SMS can be time-consuming. Our solution addresses these challenges using AWS services with fewer steps than traditional third-party options. This solution also features automatic scaling, built-in high availability, and a pay-for-use billing model to increase agility and optimize costs. These technologies not only decrease infrastructure management tasks like capacity provisioning and patching, but provides for a better customer experience.

Further reading:
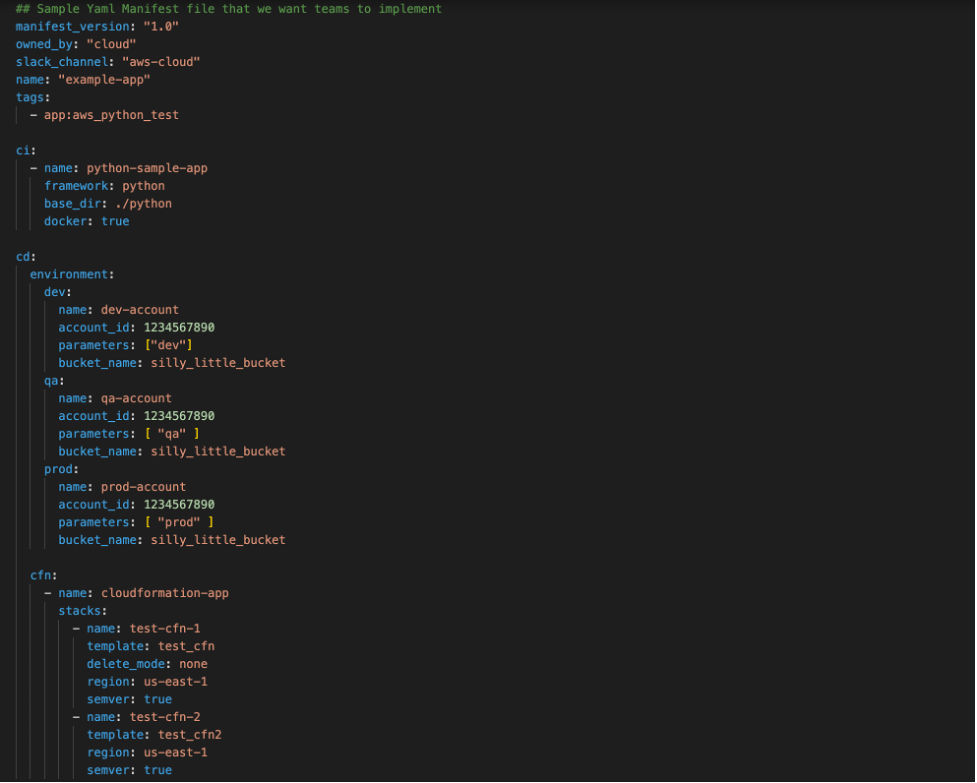
Using larger ephemeral storage for AWS Lambda

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/using-larger-ephemeral-storage-for-aws-lambda/

AWS Lambda functions have always had ephemeral storage available at /tmp in the file system. This was set at 512 MB for every function, regardless of runtime or memory configuration. With this new feature, you can now configure ephemeral storage for up to 10 GB per function instance.

You can set this in the AWS Management Console, AWS CLI, or AWS SDK, AWS Serverless Application Model (AWS SAM), AWS Cloud Development Kit (AWS CDK), AWS Lambda API, and AWS CloudFormation. This blog post explains how this works and how to use this new setting in your Lambda functions.

How ephemeral storage works in Lambda

All functions have ephemeral storage available at the fixed file system location /tmp. This provides a fast file system-based scratch area that is scoped to a specific instance of a Lambda function. This storage is not shared between instances of Lambda functions and the space is guaranteed to be empty when a new instance starts.

This means that you can use the same execution environment to cache static assets in /tmp between invocations. This is a common use case that can help reduce function duration for subsequent invocations. The contents are deleted when the Lambda service eventually terminates the execution environment.

With this new configurable setting, ephemeral storage works in the same way. The behavior is identical whether you use zip or container images to deploy your functions. It’s also available for Provisioned Concurrency. All data stored in /tmp is encrypted at rest with a key managed by AWS.

Common use cases for ephemeral storage

There are three common customer use cases that can benefit from the expanded ephemeral storage.

Extract-transform-load (ETL) jobs: Your code may perform intermediate computation or download other resources to complete processing. More temporary space enables more complex ETL jobs to run in Lambda functions.

Machine learning (ML) inference: Many inference tasks rely on large reference data files, including libraries and models. More ephemeral storage allows you to download larger models from Amazon S3 to /tmp and use these in your processing. To learn more about using Lambda for ML inference, read Building deep learning inference with AWS Lambda and Amazon EFS and Pay as you go machine learning inference with AWS Lambda.

Data processing: For workloads that download objects from S3 in response to S3 events, the larger /tmp space makes it possible to handle larger objects without using in-memory processing. Workloads that create PDFs, use headless Chromium, or process media also benefit from more ephemeral storage.

Zip processing: Some workloads use large zip files from data providers to initialize local databases. These can now unzip to the local file system without the need for in-memory processing. Similarly, applications that generate zip files also benefit from more /tmp space.

Graphics processing: Image processing is a common use-case for Lambda-based applications. For workloads processing large tiff files or satellite images, this makes it easier to use libraries like ImageMagick to perform all the computation in Lambda. Customers using geospatial libraries also gain significant flexibility from writing large satellite images to /tmp.

Deploying the example application

The example application shows how to resize an MP4 file from Amazon S3, using the temporary space for intermediate processing. In this example, you can process video files much larger than the standard 512 MB temporary storage:

Example application architecture

Before deploying the example, you need:

This example uses the AWS Serverless Application Model (AWS SAM). To deploy:

  1. From a terminal window, clone the GitHub repo:
    git clone https://github.com/aws-samples/s3-to-lambda-patterns
  2. Change directory to this example:
    cd ./resize-video
  3. Follow the installation instructions in the README file.

To test the application, upload an MP4 file into the source S3 bucket. After processing, the destination bucket contains the resized video file.

How the example works

The resize function downloads the original video from S3 and saves the result in Lambda’s temporary storage directory:

	// Get signed URL for source object
	const Key = decodeURIComponent(record.s3.object.key.replace(/\+/g, ' '))

	const data = await s3.getObject({
		Bucket: record.s3.bucket.name,
		Key
	}).promise()

	// Save original to tmp directory
	const tempFile = `${ffTmp}/${Key}`
	console.log('Saving downloaded file to ', tempFile)
	fs.writeFileSync(tempFile, data.Body)

The application uses FFmpeg to resize the video and store the output in the temporary storage space:

// Save resized video to /tmp
	const outputFilename = `${Key.split('.')[0]}-smaller.mp4`
	console.log(`Resizing and saving to ${outputFilename}`)
	await execPromise(`${ffmpegPath} -i "${tempFile}" -loglevel error -vf scale=160:-1 -sws_flags fast_bilinear ${ffTmp}/${outputFilename}`)

After processing, the function reads the file from the temporary directory and then uploads to the destination bucket in S3:

	const tmpData = fs.readFileSync(`${ffTmp}/${outputFilename}`)
	console.log(`tmpData size: ${tmpData.length}`)

	// Upload to S3
	console.log(`Uploading ${outputFilename} to ${outputFilename}`)
	await s3.putObject({
		Bucket: process.env.OutputBucketName,
		Key: outputFilename,
		Body: tmpData
	}).promise()
	console.log(`Object written to ${process.env.OutputBucketName}`)

Since temporary storage is not deleted between warm Lambda invocations, you may also choose to remove unneeded files. This example uses a tmpCleanup function to delete the contents of /tmp:

const fs = require('fs')
const path = require('path')
const directory = '/tmp/'

// Deletes all files in a directory
const tmpCleanup = async () => {
	console.log('Starting tmpCleanup')
	fs.readdir(directory, (err, files) => {
		return new Promise((resolve, reject) => {
			if (err) reject(err)

			console.log('Deleting: ', files)				
			for (const file of files) {
				const fullPath = path.join(directory, file)
				fs.unlink(fullPath, err => {
					if (err) reject (err)
				})
			}
			resolve()
		})
	})
}

Setting ephemeral storage with the AWS Management Console or AWS CLI

In the Lambda console, you can view the ephemeral storage allocated to a function in the Generation configuration menu in the Configuration tab:

Lambda function configuration

To make changes to this setting, choose Edit. In the Edit basic settings page, adjust the Ephemeral Storage to any value between 512 MB and 10240 MB. Choose Save to update the function’s settings.

Basic settings

You can also define the ephemeral storage setting in the create-function and update-function-configuration CLI commands. In both cases, use the ephemeral-storage switch to set the value:

aws lambda create-function --function-name testFunction --runtime python3.9 --handler lambda_function.lambda_handler --code S3Bucket=myBucket,S3Key=function.zip --role arn:aws:iam::123456789012:role/testFunctionRole --ephemeral-storage '{"Size": 10240}' 

To modify this setting for testFunction, run:

aws lambda update-function-configuration --function-name testFunction --ephemeral-storage '{"Size": 5000}'

Setting ephemeral storage with AWS CloudFormation or AWS SAM

You can define the size of ephemeral storage in both AWS CloudFormation and AWS SAM templates by using the EphemeralStorage attribute. As shown in the example’s template.yaml, there is a new attribute called EphemeralStorage:

  ResizeFunction:
    Type: AWS::Serverless::Function
    Properties:
      CodeUri: resizeFunction/
      Handler: app.handler
      Runtime: nodejs14.x
      Timeout: 900
      MemorySize: 10240
      EphemeralStorage:
        Size: 10240

You define this on a per-function basis. If the attribute is missing, the function is allocated 512 MB of temporary storage.

Using Lambda Insights to monitor temporary storage usage

You can use Lambda Insights to query on the metrics emitted by the Lambda function relating to the usage of temporary storage. First, enable Lambda Insights on a function by following these steps in the documentation.

After running the function, the Lambda service writes ephemeral storage metrics to Amazon CloudWatch Logs. With Lambda Insights enabled, you can now query these from the CloudWatch console. From the Logs Insights feature, you can query to determine the maximum, used, and available space available:

fields @timestamp,
tmp_max/(1024*1024),
tmp_used/(1024*1024),
tmp_free/(1024*1024)

Calculating the cost of more temporary storage

Ephemeral storage is free up to 512 MB, as it always has been. You are charged for the amount you select between 512 MB and 10,240 MB. For example, if you select 1,024 MB, you only pay for 512 MB. Expanded ephemeral storage costs $0.0000000308 per GB/second in the us-east-1 Region (see the pricing page for other Regions).

In us-east-1, for a workload invoking a Lambda function 500,000 times with a 10 second duration, using the maximum temporary storage, the cost is $0.63:

Invocations 500,000
Duration (ms) 10,000
Ephemeral storage (over 512 MB) 9,728
Storage price per GB/s $0.0000000308
GB/s total 20,480,000
Price of storage $0.63

Choosing between ephemeral storage and Amazon EFS

Generally, ephemeral storage is designed for intermediary processing of a function. You can download reference data, machine learning models, or database metadata from other sources such as Amazon S3, and store these in /tmp for further processing. Ephemeral storage can provide a cache for data for repeat usage across invocations and offers fast I/O throughout.

Alternatively, EFS is primarily intended for customers that need to:

  • Share data or state across function invocations.
  • Process files larger than the 10,240 MB storage allows.
  • Use file-system type functionality, such as appending to or modifying files.

Conclusion

Serverless developers can now configure the amount of temporary storage available in AWS Lambda functions. This blog post discusses common use cases and walks through an example application that uses larger temporary storage. It also shows how to configure this in CloudFormation and AWS SAM and explains the cost if you use more than the free, provisioned 512 MB that’s automatically provisioned for every function.

For more serverless learning resources, visit Serverless Land.

Dream11: Blocking application attacks using AWS WAF at scale

Post Syndicated from Vatsal Shah original https://aws.amazon.com/blogs/architecture/dream11-blocking-application-attacks-using-aws-waf-at-scale/

As the world’s largest fantasy sports platforms with more than 120 million registered users, Dream11 runs multiple contests simultaneously while processing millions of user requests per minute. Their user-centric and data-driven teams make it a priority to ensure that the Dream11 application (app) remains protected against all kinds of threats and vulnerabilities.

Introduction to AWS WAF Security Automations

AWS WAF is a web application firewall that helps protect apps and APIs against common web exploits and bots. These attacks may affect availability, compromise security, or consume excessive resources. AWS WAF gives you control over how traffic reaches your applications. You can create security rules that control bot traffic and block common attack patterns, such as SQL injection or cross-site scripting (XSS.)

AWS WAF Security Automations use AWS CloudFormation to quickly configure AWS WAF rules that help block the following common types of attacks:

  • SQL injection
  • Cross-site scripting
  • HTTP floods
  • Scanners and probes
  • Known attacker origins (IP reputation lists)
  • Bots and scrapers

In this blog post, we will explain how Dream11 uses AWS WAF Security Automations to protect its application from scanners and probes attacks.

Scanner and probe automation

To understand the scanner and probe automation, let’s look at a realistic attack scenario for a standard app that is protected by AWS WAF. Let’s assume that a malicious user is trying to scan the app and identify loopholes using their custom tool. They plan to conduct injection attacks (such as SQLi, XSS) or directory brute force attacks.

The app, secured by AWS WAF, has rules in place to block requests if certain signatures and patterns are matched. AWS WAF cannot have all possible payload lists for each attack vector. This means that after some trial and errors, an attacker may find the payload that doesn’t get blocked by AWS WAF and try to exploit the vulnerability.

In this case, what if AWS WAF can detect the behavior of malicious user IPs and block it for a certain time period? Wouldn’t it be great if AWS WAF blocks the IP of a malicious user after receiving a couple of malicious requests? That way, new requests coming from that IP will be blocked without AWS WAF having to check all the rules in the web ACL. Any successful bypass attempts will also get blocked from that IP. Rather than permanently blocking the IP, this feature blocks the offending IP for a certain time period, discouraging the attacker from any further attempts. It acts as a first step of incident response. Here’s where automation can help.

Scanner and probe automation monitors Amazon CloudFront logs and analyses HTTP status codes for requests coming from different IPs. Based on the configured threshold of HTTP status codes, scanner and probe automation will update the malicious IP directly to the AWS WAF rule IPSet. It then blocks subsequent requests from that IP for a configured period of time.

The AWS WAF Security Automations solution creates an AWS WAF rule, an AWS Lambda function, and a Scanner and Probes Amazon Athena query. The Athena query parses Amazon CloudFront or Application Load Balancer access logs at regular intervals. It counts the number of bad requests per minute from unique source IP addresses. The Lambda function updates the AWS WAF IPSet rule to block further scans from IP addresses with a high error rate.

Scanner and probe solution

Solution architecture for scanner and probe automation (xxx represents the numbers as defined by the use case)

Figure 1. Solution architecture for scanner and probe automation (xxx represents the numbers as defined by the use case)

The workflow of the solution is as follows, shown in Figure 1:

  • CloudFront logs are pushed to the Amazon S3 bucket
  • Log Parser Lambda will run the Athena query to find the error code threshold for each unique IP
  • If the HTTP error threshold is crossed for any IP, the Lambda function will update the IP into an AWS WAF IPSet for a certain time
  • The IPSet is unblocked automatically after the time period is over

Customizing the AWS WAF Security Automation solution

Scanner and probe automation with rules will block traffic if the error rate for a particular IP crosses the threshold. It then adds the IP in the blocked IPSet. This IP is blocked for a configurable amount of time (for example, 12 hours, 2 days, 1 week).

During the customization of AWS WAF for Dream11, there were instances which required exceptions to the preceding rule. One was to prevent internal services/gateway IPs from getting blocked by the security automation. We needed to customize the rules for these predefined thresholds. For example: the solution should block the external traffic, but exclude any internal IP addresses.

The Dream11 Security team customized the Lambda logic to approve all internal NAT gateway IPs. Scanner and probe automation ignores these IPs even if there is a high number of errors from the approved IPs. Sample code is as follows:

log.info("[update_ip_set] \tIgnore the approved IP ")

if ip_type == "IPV4" and source_ip not in outstanding_requesters['ApprovedIPs']:  
                addresses_v4.append(source_ip)
elif ip_type == "IPV6" and source_ip not in outstanding_requesters['ApprovedIPs']:                     addresses_v6.append(source_ip)

Note: Create a JSON file with list of approved IPs and store it in APP_ACCESS_LOG_BUCKET
We will use the same S3 bucket to put our office-approved IPs as xyz.json file where we store our CloudFront access logs. This is configurable during CloudFormation template for Security Automation.

Code explanation:

  1. The custom code first validates the particular IP for which the error threshold is crossed against the approved IPs.
  2. If the IP belongs to the IPV4 or IPV6 format and isn’t an approved IP, it will be appended to the blocked IPSet for a certain period of time.

The customization of the Lambda function provides a security automation solution that doesn’t block any legitimate request. At the same time, it provides protection against scanner and probe attacks. AWS WAF security automation is an open-source solution and is hosted on GitHub.

Conclusion

In this blog post, we’ve given a brief overview of how you can reduce attacks by using AWS WAF Security Automations against scanners and probes. We’ve also illustrated the customization implemented by the Dream11 security team.

By automating your security operations, you will improve effective incident response. You can prioritize threats and handle cyber attacks automatically with automated courses of action. This reduces the need for human intervention, reduces response time, and addresses security issues without manual effort.

After implementing this at Dream11, we were able to create custom, application-specific rules that blocked attack patterns. This has provided application availability, secure resources, and has prevented excessive resource consumption. With this solution, we are able to provide the best fantasy sports experience for over 120 million users.

Read more about Security Automations in AWS WAF.

AWS Lambda Now Supports Up to 10 GB Ephemeral Storage

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/aws-lambda-now-supports-up-to-10-gb-ephemeral-storage/

Serverless applications are event-driven, using ephemeral compute functions ranging from web APIs, mobile backends, and streaming analytics to data processing stages in machine learning (ML) and high-performance applications. While AWS Lambda includes a 512 MB temporary file system (/tmp) for your code, this is an ephemeral scratch resource not intended for durable storage such as Amazon Elastic File System (Amazon EFS).

However, extract, transform, and load (ETL) jobs and content generation workflows such as creating PDF files or media transcoding require fast, scalable local storage to process large amounts of data quickly. Data-intensive applications require large amounts of temporary data specific to the invocation or cached data that can be reused for all invocation in the same execution environment in a highly performant manner. With the previous limit of 512 MB, customers had to selectively load data from Amazon Simple Storage Service (Amazon S3) and Amazon EFS, or increase the allocated function memory and thus increase their cost, just to handle large objects downloaded from Amazon S3. Since customers could not cache larger data locally in the Lambda execution environment, every function invoke had to read data in parallel, which made scaling out harder for customers.

Today, we are announcing that AWS Lambda now allows you to configure ephemeral storage (/tmp) between 512 MB and 10,240 MB. You can now control the amount of ephemeral storage a function gets for reading or writing data, allowing you to use AWS Lambda for ETL jobs, ML inference, or other data-intensive workloads.

With increased AWS Lambda ephemeral storage, you get access to a secure, low-latency ephemeral file system up to 10 GB. You can continue to use up to 512 MB for free and are charged for the amount of storage you configure over the free limit for the duration of invokes.

Setting Larger Ephemeral Storage for Your Lambda Function
To configure your Lambda function with larger ephemeral storage, choose the Configuration tab under the General Configuration section in the AWS Lambda Console. You will see a new configuration for Ephemeral storage setting at 512MB by default.

When you click the Edit button, you can configure the ephemeral storage from 512 MB to 10,240 MB in 1 MB increments for your Lambda functions.

With AWS Command Line Interface (AWS CLI), you can update your desired size of ephemeral storage using theupdate-function-configuration command.

$ aws lambda update-function-configuration --function-name PDFGenerator \
              --ephemeral-storage '{"Size": 10240}'

You can configure ephemeral storage using Lambda API via AWS SDK and AWS CloudFormation. To learn more, see Configuring function options in the AWS Documentation.

As a review, AWS Lambda provides a comprehensive range of storage options. To learn more, see a great blog post, Choosing between AWS Lambda data storage options in web apps, written by my colleague James Beswick. I want to quote the table to show the differences between these options and common use-cases to help you choose the right one for your own applications.

Features Ephemeral Storage (/tmp) Lambda Layers Amazon EFS Amazon S3
Maximum size 10,240 MB 50 MB (direct upload) Elastic Elastic
Persistence Ephemeral Durable Durable Durable
Content Dynamic Static Dynamic Dynamic
Storage type File system Archive File system Object
Lambda event source integration N/A N/A N/A Native
Operations supported Any file system operation Immutable Any file system operation Atomic with versioning
Object tagging and metadata
N N N Y
Pricing model Included in Lambda
(Charged over 512MB)
Included in Lambda Storage + data transfer + throughput Storage + requests + data transfer
Shared across all invocations N Y Y Y
Sharing/permissions model Function-only IAM IAM + NFS IAM
Source for AWS Glue and Amazon Quicksight
N N N Y
Relative data access speed from Lambda Fastest Fastest Very fast Fast

Available Now
You can now configure up to 10 GB of ephemeral storage per Lambda function instance in all Regions where AWS Lambda is available. With 10 GB container image support, 10 GB function memory, and now 10 GB of ephemeral function storage, you can support workloads such as using large temporal files, data and media processing, machine learning inference, and financial analysis.

Support is also available through many AWS Lambda Partners such as HashiCorp (Terraform), Pulumi, Datadog, Splunk (SignalFx), Lumigo, Thundra, Dynatrace, Slalom, Cloudwiry, and Contino.

For this feature, you are charged for the storage you configure over the 512 MB free limit for the duration of your function invokes. To learn more, visit AWS Lambda product and pricing page and send feedback through the AWS re:Post for AWS Lambda or your usual AWS Support contacts.

– Channy

Choosing the right solution for AWS Lambda external parameters

Post Syndicated from Julian Wood original https://aws.amazon.com/blogs/compute/choosing-the-right-solution-for-aws-lambda-external-parameters/

This post is written by Thomas Moore, Solutions Architect, Serverless.

When using AWS Lambda to build serverless applications, customers often need to retrieve parameters from an external source at runtime. This allows you to share parameter values across multiple functions or microservices, providing a single source of truth for updates. A common example is retrieving database connection details from an external source and then using the retrieved hostname, user name, and password to connect to the database:

Lambda function retrieving database credentials from an external source

Lambda function retrieving database credentials from an external source

AWS provides a number of options to store parameter data, including AWS Systems Manager Parameter Store, AWS AppConfig, Amazon S3, and Lambda environment variables. This blog explores the different parameter data that you may need to store. I cover considerations for choosing the right parameter solution and how to retrieve and cache parameter data efficiently within the Lambda function execution environment.

Common use cases

Common parameter examples include:

  • Securely storing secret data, such as credentials or API keys.
  • Database connection details such as hostname, port, and credentials.
  • Schema data (for example, a structured JSON response).
  • TLS certificate for mTLS or JWT validation.
  • Email template.
  • Tenant configuration in a multitenant system.
  • Details of external AWS resources to communicate with such as an Amazon SQS queue URL, Amazon EventBridge event bus name, or AWS Step Functions ARN.

Key considerations

There are a number of key considerations when choosing the right solution for external parameter data.

  1. Cost – how much does it cost to store the data and retrieve it via an API call?
  2. Security – what encryption and fine-grained access control is required?
  3. Performance – what are the retrieval latency requirements?
  4. Data size – how much data is there to store and retrieve?
  5. Update frequency – how often does the parameter change and how does the function handle stale parameters?
  6. Access scope – do multiple functions or services access the parameter?

These considerations help to determine where to store the parameter data and how often to retrieve it.

For example, a 4KB parameter that updates hourly and is used by hundreds of functions needs to be optimized for low retrieval costs and high performance. Choosing a solution that supports low-cost API GET requests at a high transaction per second (TPS) would be better than one that supports large data.

AWS service options

There are a number of AWS services available to store external parameter data.

Amazon S3

S3 is an object storage service offering 99.999999999% (11 9s) of data durability and virtually unlimited scalability at low cost. Objects can be up to 5 TB in size in any format, making S3 a good solution to store larger parameter data.

Amazon DynamoDB

Amazon DynamoDB is a fully managed, serverless, key-value NoSQL database designed for single-digit millisecond performance at any scale. Due to the high performance of this service, it’s a great place to store parameters when low retrieval latency is important.

AWS Secrets Manager

AWS Secrets Manager makes it easier to rotate, manage, and retrieve secret data. This makes it the ideal place to store sensitive parameters such as passwords and API keys.

AWS Systems Manager Parameter Store

Parameter Store provides a centralized store to manage configuration data. This data can be plaintext or encrypted using AWS Key Management Service (KMS). Parameters can be tagged and organized into hierarchies for simpler management. Parameter Store is a good default choice for general-purpose parameters in AWS. The standard version (no additional charge) can store parameters up to 4 KB in size and the advanced version (additional charges apply) up to 8 KB.

For a code example using Parameter Store for Lambda parameters, see the Serverless Land pattern.

AWS AppConfig

AppConfig is a capability of AWS Systems Manager to create, manage, and quickly deploy application configurations. AppConfig allows you to validate changes during roll-outs and automatically roll back, if there is an error. AppConfig deployment strategies help to manage configuration changes safely.

AppConfig also provides a Lambda extension to retrieve and locally cache configuration data. This results in fewer API calls and reduced function duration, reducing costs.

AWS Lambda environment variables

You can store parameter data as Lambda environment variables as part of the function’s version-specific configuration. Lambda environment variables are stored during function creation or updates. You can access these variables directly from your code without needing to contact an external source. Environment variables are ideal for parameter values that don’t need updating regularly and help make function code reusable across different environments. However, unlike the other options, values cannot be accessed centrally by multiple functions or services.

Lambda execution lifecycle

It is worth understanding the Lambda execution lifecycle, which has a number of stages. This helps to decide when to handle parameter retrieval within your Lambda code, including cache management.

Lambda execution lifecycle

Lambda execution lifecycle

When a Lambda function is invoked for the first time, or when Lambda is scaling to handle additional requests, an execution environment is created. The first phase in the execution environment’s lifecycle is initialization (Init), during which the code outside the main handler function runs. This is known as a cold start.

The execution environment can then be re-used for subsequent invocations. This means that the Init phase does not need to run again and only the main handler function code runs. This is known as a warm start.

An execution environment can only run a single invocation at a time. Concurrent invocations require additional execution environments. When a new execution environment is required, this starts a new Init phase, which runs the cold start process.

Caching and updates

Retrieving the parameter during Init

Retrieving the parameter during Init

Retrieving the parameter during Init

As Lambda execution environments are re-used, you can improve the performance and reduce the cost of retrieving an external parameter by caching the value. Writing the value to memory or the Lambda /tmp file system allows it to be available during subsequent invokes in the same execution environment.

This approach reduces API calls, as they are not made during every invocation. However, this can cause an out-of-date parameter and potentially different values across concurrent execution environments.

The following Python example shows how to retrieve a Parameter Store value outside the Lambda handler function during the Init phase.

import boto3
ssm = boto3.client('ssm', region_name='eu-west-1')
parameter = ssm.get_parameter(Name='/my/parameter')
def lambda_handler(event, context):
    # My function code...

Retrieving the parameter on every invocation

Retrieving the parameter on every invocation

Retrieving the parameter on every invocation

Another option is to retrieve the parameter during every invocation by making the API call inside the handler code. This keeps the value up to date, but can lead to higher retrieval costs and longer function durations due to the added API call during every invocation.

The following Python example shows this approach:

import boto3
ssm = boto3.client('ssm', region_name='eu-west-1')
def lambda_handler(event, context):
    parameter = ssm.get_parameter(Name='/my/parameter')
    # My function code...

Using AWS AppConfig Lambda extension

Using AWS AppConfig Lambda extension

Using AWS AppConfig Lambda extension

AppConfig allows you to retrieve and cache values from the service using a Lambda extension. The extension retrieves the values and makes them available via a local HTTP server. The Lambda function then queries the local HTTP server for the value. The AppConfig extension refreshes the values at a configurable poll interval, which defaults to 45 seconds. This improves performance and reduces costs, as the function only needs to make a local HTTP call.

The following Python code example shows how to access the cached parameters.

import urllib.request
def lambda_handler(event, context):
    url = f'http://localhost:2772/applications/application_name/environments/environment_name/configurations/configuration_name'
    config = urllib.request.urlopen(url).read()
    # My function code...

For caching secret values using a Lambda extension local HTTP cache and AWS Secrets Manager, see the AWS Prescriptive Guidance documentation.

Using Lambda Powertools for Python or Java

Lambda Powertools for Python or Lambda Powertools for Java contains utilities to manage parameter caching. You can configure the cache interval, which defaults to 5 seconds. Supported parameter stores include Secrets Manager, AWS Systems Manager Parameter Store, AppConfig, and DynamoDB. You also have the option to bring your own provider. The following example shows the Powertools for Python parameters utility retrieving a single value from Systems Manager Parameter Store.

from aws_lambda_powertools.utilities import parameters
def handler(event, context):
    value = parameters.get_parameter("/my/parameter")
    # My function code…

Security

Parameter security is a key consideration. You should evaluate encryption at rest, in-transit, private network access, and fine-grained permissions for each external parameter solution based on the use case.

All services highlighted in this post support server-side encryption at rest, and you can choose to use AWS KMS to manage your own keys. When accessing parameters using the AWS SDK and CLI tools, connections are encrypted in transit using TLS by default. You can force most to use TLS 1.2.

To access parameters from inside an Amazon Virtual Private Cloud (Amazon VPC) without internet access, you can use AWS PrivateLink and create a VPC endpoint for each service. All the services mentioned in this post support AWS PrivateLink connections.

Use AWS Identity and Access Management (IAM) policies to manage which users or roles can access specific parameters.

General guidance

This blog explores a number of considerations to make when using an external source for Lambda parameters. The correct solution is use-case dependent. There are some general guidelines when selecting an AWS service.

  • For general-purpose low-cost parameters, use AWS Systems Manager Parameter Store.
  • For single function, small parameters, use Lambda environment variables.
  • For secret values that require automatic rotation, use AWS Secrets Manager.
  • When you need a managed cache, use the AWS AppConfig Lambda extension or Lambda Powertools for Python/Java.
  • For items larger than 400 KB, use Amazon S3.
  • When access frequency is high, and low latency is required, use Amazon DynamoDB.

Conclusion

External parameters provide a central source of truth across distributed systems, allowing for efficient updates and code reuse. This blog post highlights a number of considerations when using external parameters with Lambda to help you choose the most appropriate solution for your use case.

Consider how you cache and reuse parameters inside the Lambda execution environment. Doing this correctly can help you reduce costs and improve the performance of your Lambda functions.

There are a number of services to choose from to store parameter data. These include DynamoDB, S3, Parameter Store, Secrets Manager, AppConfig, and Lambda environment variables. Each comes with a number of advantages, depending on the use case. This blog guidance, along with the AWS documentation and Service Quotas, can help you select the most appropriate service for your workload.

For more serverless learning resources, visit Serverless Land.

Deploy Quarkus-based applications using AWS Lambda with AWS SAM

Post Syndicated from Joan Bonilla original https://aws.amazon.com/blogs/architecture/deploy-quarkus-based-applications-using-aws-lambda-with-aws-sam/

­Quarkus offers Java developers the capability of building native images based on GraalVM. A native image is a binary that includes everything: your code, libraries, and a smaller virtual machine (VM). This approach improves the startup time of your AWS Lambda functions, because it is optimized for container-based environments. These use cloud native and serverless architectures with a container-first philosophy.

In this blog post, you learn how to integrate the Quarkus framework with AWS Lambda functions, using the AWS Serverless Application Model (AWS SAM).

Reduce infrastructure costs and improve latency

When you develop applications with Quarkus and GraalVM with native images, the bootstrap file generated requires more time to compile, but it has a faster runtime. GraalVM is a JIT compiler that generates optimized native machine code that provides different garbage collector implementations, and uses less memory and CPU. This is achieved with a battery of advanced compiler optimizations and aggressive and sophisticated inlining techniques. By using Quarkus, you can also reduce your infrastructure costs because you need less resources.

With Quarkus and AWS SAM features, you can improve the latency performance of your Java-based AWS Lambda functions by reducing the cold-start time. A cold-start is the initialization time that a Lambda function takes before running the actual code. After the function is initialized for the first time, future requests will reuse the same execution environment without incurring the cold-start time, leading to improved performance.

Overview of solution

Figure 1 shows the AWS components and workflow of our solution.

Architecture diagram deploying an AWS SAM template using the Amazon API Gateway and AWS Lambda services with Amazon CloudWatch metrics

Figure 1. Architecture diagram for Quarkus (AWS Lambda) application

With AWS SAM, you can easily integrate external frameworks by using custom runtimes and configuring properties in the template file and the Makefile.

Prerequisites

For this walkthrough, you should have the following prerequisites:

Creating a Java-based AWS Lambda function

AWS SAM provides default templates to accelerate the development of new functions. Create a Java-based function by following these steps:

Run the following command in your terminal:

sam init -a x86_64 -r java11 -p Zip -d maven -n java11-mvn-default

These parameters select a x86 architecture, java11 as Java runtime LTS version, Zip as a build artifact, and Maven as the package and dependency tool. It also defines the project name.

Choose the first option to use a template for your base code:

1 – AWS Quick Start Templates

Finally, with the previous selection you have different templates to choose from to create the base structure of your function. In our case, select the first one, which creates an AWS Lambda function calling an external HTTPS endpoint. This will get the IP address and return it with a “Hello World” response to the user in JSON:

1 – Hello World Example

The output will yield the following, shown in Figure 2:

AWS SAM input fields to select the programming language, the build artifact, the project name and the dependency tool for our sample.

Figure 2. AWS SAM configuration input data

Integrating Quarkus framework

Using AWS SAM, you can easily integrate non-AWS custom runtimes in your AWS Lambda functions. With this feature, you can integrate the Quarkus framework. Follow the next four steps:

1. Create a Makefile file

Create a “Makefile” file in the “HelloWorldFunction” directory with this code:

  build-HelloWorldFunction:
  mvn clean package -Pnative -Dquarkus.native.container-build=true -Dquarkus.native.builder-image=quay.io/quarkus/ubi-quarkus-mandrel:21.3-java11
  @ unzip ./target/function.zip -d $(ARTIFACTS_DIR)

With this snippet, you are configuring AWS SAM to build the bootstrap runtime using Maven instructions for AWS SAM.

Using Quarkus, you can build a Linux executable without having to install GraalVM with the next option:

  -Dquarkus.native.container-build=true

For more information, you can visit the official site and learn more about building a native image.

2. Configure Maven dependencies

As a Maven project, include the necessary dependencies. Change the pom.xml file in the “HelloWorldFunction” directory to remove the default libraries:

<dependencies>
  <dependency>
    <groupId>com.amazonaws</groupId>
    <artifactId>aws-lambda-java-core</artifactId>
    <version>1.2.1</version>
  </dependency>
  <dependency>
    <groupId>com.amazonaws</groupId>
    <artifactId>aws-lambda-java-events</artifactId>
    <version>3.6.0</version>
  </dependency>
</dependencies>

Add the Quarkus libraries, profile, and plugins in the right pom.xml section as shown in the following XML configuration. At the current time, the latest version of Quarkus is 2.7.1.Final. We highly recommend using the latest versions of the libraries and plugins:

<dependencies>
  <dependency>
    <groupId>io.quarkus</groupId>
    <artifactId>quarkus-amazon-lambda</artifactId>
    <version>2.7.1.Final</version>
  </dependency>
  <dependency>
    <groupId>io.quarkus</groupId>
    <artifactId>quarkus-arc</artifactId>
    <version>2.7.1.Final</version>
  </dependency>
  <dependency>
    <groupId>junit</groupId>
    <artifactId>junit</artifactId>
    <version>4.13.1</version>
    <scope>test</scope>
  </dependency>
</dependencies>

<build>
  <finalName>function</finalName>
  <plugins>
    <plugin>
      <groupId>io.quarkus</groupId>
      <artifactId>quarkus-maven-plugin</artifactId>
      <version>2.7.1.Final</version>
      <extensions>true</extensions>
      <executions>
        <execution>
          <goals>
            <goal>build</goal>
            <goal>generate-code</goal>
            <goal>generate-code-tests</goal>
          </goals>
        </execution>
      </executions>
    </plugin>
  </plugins>
</build>

<profiles>
  <profile>
    <id>native</id>
    <activation>
      <property>
        <name>native</name>
      </property>
    </activation>
    <properties>
      <quarkus.package.type>native</quarkus.package.type>
    </properties>
  </profile>
</profiles>

3. Configure the template.yaml to use the previous Makefile

To configure the AWS SAM template to use your own Makefile configuration using Quarkus and Maven instructions correctly, edit the template.yaml file to add the following properties:

Resources:
  HelloWorldFunction:
    Metadata:
      BuildMethod: makefile
    Properties:
      Runtime: provided

4. Add a new properties file to enable SSL configuration

Finally, create an application.properties file in the directory: ../HelloWorldFunction/src/main/resources/ with the following property:

quarkus.ssl.native=true

This property is needed because the sample function uses a secure connection to https://checkip.amazonaws.com. It will get the response body in the sample you selected previously.

Now you can build and deploy your first Quarkus function with the following AWS SAM commands:

sam build

This will create the Zip artifact using the Maven tool and will build the native image to deploy on AWS Lambda based on your previous Makefile configuration. Finally, run the following AWS SAM command to deploy your function:

sam deploy -–guided

The first time you deploy an AWS SAM application, you can customize some configurations or parameters like the Stack name, the AWS Region, and more (see Figure 3). You can also accept the default one. For more information about AWS SAM deploy options, read the AWS SAM documentation.

AWS SAM input fields to configure the deployment options in our sample.

Figure 3. Lambda deployment configuration input data

This sample configuration enables you to configure the necessary IAM permissions to deploy the AWS SAM resources for this sample. After completing the task, you can see the AWS CloudFormation Stack and resources created by AWS SAM.

You have now created and deployed an HTTPS API Gateway endpoint with a Quarkus application on AWS Lambda that you can test.

Testing your Quarkus function

Finally, test your Quarkus function in the AWS Management Console by selecting the new function in the AWS Lambda functions list. Use the test feature included in the console, as shown in Figure 4:

Test Quarkus execution result succeeded showing the response body returning the IP address.

Figure 4. Lambda execution test example

You will get a response to your Lambda request and a summary. This includes information like duration, or resources needed in your new Quarkus function. For more information about testing applications on AWS SAM, you can read Testing and debugging serverless applications. You can also visit the official site to read more information using AWS SAM with Quarkus.

Cleaning up

To avoid incurring future charges, delete the resources created in your AWS Lambda stack. You can delete resources with the following command:

sam delete

Conclusion

In this post, we demonstrated how to integrate Java frameworks like Quarkus on AWS Lambda using custom runtimes with AWS SAM. This enables you to configure custom build configurations or your preferred frameworks. These tools improve the developer experience, standardizing the tool used to develop serverless applications with future requirements, showing a strong flexibility for developers.

The Quarkus native image generated and applied in the AWS Lambda function reduces the heavy Java footprint. You can use your Java skills to develop serverless applications without having to change the programming language. This is a great advantage when cold-starts or compute resources are important for business or technical requirements.

Implementing mutual TLS for Java-based AWS Lambda functions

Post Syndicated from Julian Wood original https://aws.amazon.com/blogs/compute/implementing-mutual-tls-for-java-based-aws-lambda-functions-2/

This post is written by Dhiraj Mahapatro, Senior Specialist SA, Serverless and Christian Mueller, Principal Solutions Architect

Modern secure applications establish network connections to other services through HTTPS. This ensures that the application connects to the right party and encrypts the data before sending it over the network.

You might not want unauthenticated users to connect to your service as a service provider. One solution to this requirement is to use mutual TLS (Transport Layer Security). Mutual TLS (or mTLS) is a common security mechanism that uses client certificates to add an authentication layer. This allows the service provider to verify the client’s identity cryptographically.

The purpose of mutual TLS in serverless

mTLS refers to two parties authenticating each other at the same time when establishing a connection. By default, the TLS protocol only proves the identity of the server to a client using X.509 certificates. With mTLS, a client must prove its identity to the server to communicate. This helps support a zero-trust policy to protect against adversaries like man-in-the-middle attacks.

mTLS is often used in business-to-business (B2B) applications and microservices, where interservice communication needs mutual authentication of parties. In Java, you see the following error when the server expects a certificate, but the client does not provide one:

PKIX path building failed: sun.security.provider.certpath.SunCertPathBuilderException: unable to find valid certification path to requested target

This blog post explains multiple ways to implement a Java-based AWS Lambda function that uses mTLS to authenticate with a third-party internal or external service. The sample application and this post explain the advantages and tradeoffs of each approach.

The KeyStore and TrustStore in Java

The TrustStore is used to store certificate public keys from a certificate authority (CA) or trusted servers. A client can verify the public certificate presented by the server in a TLS connection. A KeyStore stores private key and identity certificates that a specific application uses to prove the client’s identity.

The stores contain opposite certificates. The TrustStore holds the identification certificates that identify others, while the KeyStore holds the identification certificates that identify itself.

Overview

To start, you create certificates. For brevity, this sample application uses a script that uses OpenSSL and Java’s keytool for self-signed certificates from a CA. You store the generated keys in Java KeyStore and TrustStore. However, the best practice for creating and maintaining certificates and private CA is to use AWS Certificate Manager and AWS Certificate Manager Private Certificate Authority.

You can find the details of the script in the README file.

The following diagram shows the use of KeyStore and TrustStore in the client Lambda function, and the server running on Fargate.

KeyStore and TrustStore

KeyStore and TrustStore

The demo application contains several Lambda functions. The Lambda functions act as clients to services provided by Fargate behind an Amazon Network Load Balancer (NLB) running in a private Amazon VPC. Amazon Route 53 private hosted zones are used to resolve selected hostnames. You attach the Lambda functions to this VPC to resolve the hostnames for the NLB. To learn more, read how AWS Lambda uses Hyperplane elastic network interfaces to work with custom VPC.

The following examples refer to portions of InfrastructureStack.java and the implementation in the corresponding Lambda functions.

Providing a client certificate in a Lambda function artifact

The first option is to provide the KeyStore and TrustStore in a Lambda functions’ .zip artifact. You provide specific Java environment variables within the Lambda configuration to instruct the JVM to load and trust your provided Keystore and TrustStore. The JVM uses these settings instead of the Java Runtime Environment’s (JRE) default settings (use a stronger password for your use case):

"-Djavax.net.ssl.keyStore=./client_keystore_1.jks -Djavax.net.ssl.keyStorePassword=secret -Djavax.net.ssl.trustStore=./client_truststore.jks -Djavax.net.ssl.trustStorePassword=secret"

The JRE uses this KeyStore and TrustStore to build a default SSLContext. The HttpClient uses this default SSLContext to create a TLS connection to the backend service running on Fargate.

The following architecture diagram shows the sample implementation. It consists of an Amazon API Gateway endpoint with a Lambda proxy integration that calls a backend Fargate service running behind an NLB.

Providing a client certificate in a Lambda function artifact

Providing a client certificate in a Lambda function artifact

This is a basic approach for a prototype. However, it has a few shortcomings related to security and separation of duties. The KeyStore contains the private key, and the password is exposed to the source code management (SCM) system, which is a security concern. Also, it is the Lambda function owner’s responsibility to update the certificate before its expiration. You can address these concerns about separation of duties with the following approach.

Providing the client certificate in a Lambda layer

In this approach, you separate the responsibility between two entities. The Lambda function owner and the KeyStore and TrustStore owner.

The KeyStore and TrustStore owner provides the certificates securely to the function developer who may be working in a separate AWS environment. For simplicity, the demo application uses the same AWS account.

The KeyStore and TrustStore owner achieves this by using AWS Lambda layers. The KeyStore and TrustStore owner packages and uploads the certificates as a Lambda layer and only allows access to authorized functions. The Lambda function owner does not access the KeyStore or manage its lifecycle. The KeyStore and TrustStore owner’s responsibility is to release a new version of this layer when necessary and inform users.

Providing the client certificate in a Lambda layer

Providing the client certificate in a Lambda layer

The KeyStore and TrustStore are extracted under the path /opt as part of including a Lambda layer. The Lambda function can now use the layer as:

Function lambdaLayerFunction = new Function(this, "LambdaLayerFunction", FunctionProps.builder()
  .functionName("lambda-layer")
  .handler("com.amazon.aws.example.AppClient::handleRequest")
  .runtime(Runtime.JAVA_11)
  .architecture(ARM_64)
  .layers(singletonList(lambdaLayerForService1cert))
  .vpc(vpc)
  .code(Code.fromAsset("../software/2-lambda-using-separate-layer/target/lambda-using-separate-layer.jar"))
  .memorySize(1024)
  .environment(Map.of(
    "BACKEND_SERVICE_1_HOST_NAME", BACKEND_SERVICE_1_HOST_NAME,
    "JAVA_TOOL_OPTIONS", "-Djavax.net.ssl.keyStore=/opt/client_keystore_1.jks -Djavax.net.ssl.keyStorePassword=secret -Djavax.net.ssl.trustStore=/opt/client_truststore.jks -Djavax.net.ssl.trustStorePassword=secret"
  ))
  .timeout(Duration.seconds(10))
  .logRetention(RetentionDays.ONE_WEEK)
  .build());

The KeyStore and TrustStore passwords are still supplied as environment variables and stored in the SCM system, which is against best practices. You can address this with the next approach.

Storing passwords securely in AWS Systems Manager Parameter Store

AWS Systems Manager Parameter Store provides secure, hierarchical storage for configuration data and secret management. You can use Parameter Store to store the KeyStore and TrustStore passwords instead of environment variables. The Lambda function uses an IAM policy to access Parameter Store and gets the passwords as a secure string during the Lambda initialization phase.

With this approach, you build a custom SSLContext after retrieving the KeyStore and TrustStore passwords from the Parameter Store. Once you create SSLContext, provide that to the HttpClient you use to connect with the backend service:

HttpClient client = HttpClient.newBuilder()
  .version(HttpClient.Version.HTTP_2)
  .connectTimeout(Duration.ofSeconds(5))
  .sslContext(sslContext)
  .build();

You can also use a VPC interface endpoint for AWS Systems Manager to keep the traffic from your Lambda function to Parameter Store internal to AWS. The following diagram shows the interaction between AWS Lambda and Parameter Store.

Storing passwords securely in AWS Systems Manager Parameter Store

Storing passwords securely in AWS Systems Manager Parameter Store

This approach works for Lambda functions interacting with a single backend service requiring mTLS. However, it is common in a modern microservices architecture to integrate with multiple backend services. Sometimes, these services require a client to assume different identities by using different KeyStores. The next approach explains how to handle the multiple services scenario.

Providing multiple client certificates in Lambda layers

You can provide multiple KeyStore and TrustStore pairs within multiple Lambda layers. All layers attached to a function are merged when provisioning the function. Ensure your KeyStore and TrustStore names are unique. A Lambda function can use up to five Lambda layers.

Similar to the previous approach, you load multiple KeyStores and TrustStores to construct multiple SSLContext objects. You abstract the common logic to create an SSLContext object in another Lambda layer. Now, the Lambda function calling two different backend services uses 3 Lambda layers:

  • Lambda layer for backend service 1 (under /opt)
  • Lambda layer for backend service 2 (under /opt)
  • Lambda layer for the SSL utility that takes the KeyStore, TrustStore, and their passwords to return an SSLContext object

SSL utility Lambda layer provides the getSSLContext default method in a Java interface. The Lambda function implements this interface. Now, you create a dedicated HTTP client per service.

The following diagram shows your final architecture:

Providing multiple client certificates in Lambda layers

Providing multiple client certificates in Lambda layers

Prerequisites

To run the sample application, you need:

  1. CDK v2
  2. Java 11
  3. AWS CLI
  4. Docker
  5. jq

To build and provision the stack:

  1. Clone the git repository.
  2. git clone https://github.com/aws-samples/serverless-mutual-tls.git
    cd serverless-mutual-tls
  3. Create the two root CA’s, client, and server certificates.
  4. ./scripts/1-create-certificates.sh
  5. Build and package all examples.
  6. ./scripts/2-build_and_package-functions.sh
  7. Provision the AWS infrastructure (make sure that Docker is running).
  8. ./scripts/3-provision-infrastructure.sh

Verification

Verify that the API endpoints are working and using mTLS by running these commands from the base directory:

export API_ENDPOINT=$(cat infrastructure/target/outputs.json | jq -r '.LambdaMutualTLS.apiendpoint')

To see the error when mTLS is not used in the Lambda function, run:

curl -i $API_ENDPOINT/lambda-no-mtls

The preceding curl command responds with an HTTP status code 500 and plain body as:

PKIX path building failed: sun.security.provider.certpath.SunCertPathBuilderException: unable to find valid certification path to requested target

For successful usage of mTLS as shown in the previous use cases, run:

curl -i $API_ENDPOINT/lambda-only
curl -i $API_ENDPOINT/lambda-layer
curl -i $API_ENDPOINT/lambda-parameter-store
curl -i $API_ENDPOINT/lambda-multiple-certificates

The last curl command responds with an HTTP status code 200 and body as:

[
 {"hello": "from backend service 1"}, 
 {"hello": "from backend service 2"}
]

Additional security

You can add additional controls via Java environment variables. Compliance standards like PCI DSS in financial services require customers to exercise more control over the underlying negotiated protocol and ciphers.

Some of the useful Java environment variables to troubleshoot SSL/TLS connectivity issues in a Lambda function are:

-Djavax.net.debug=all
-Djavax.net.debug=ssl,handshake
-Djavax.net.debug=ssl:handshake:verbose:keymanager:trustmanager
-Djavax.net.debug=ssl:record:plaintext

You can enforce a specific minimum version of TLS (for example, v1.3) to meet regulatory requirements:

-Dhttps.protocols=TLSv1.3

Alternatively, programmatically construct your SSLContext inside the Lambda function:

SSLContext sslContext = SSLContext.getInstance("TLSv1.3");

You can also use the following Java environment variable to limit the use of weak cipher suites or unapproved algorithms, and explicitly provide the supported cipher suites:

-Dhttps.cipherSuites=TLS_ECDHE_ECDSA_WITH_AES_128_GCM_SHA256,TLS_ECDHE_ECDSA_WITH_AES_256_GCM_SHA384,TLS_ECDHE_ECDSA_WITH_AES_128_CBC_SHA,TLS_ECDHE_ECDSA_WITH_AES_256_CBC_SHA,TLS_ECDHE_ECDSA_WITH_AES_128_CBC_SHA256,TLS_ECDHE_ECDSA_WITH_AES_256_CBC_SHA384,TLS_ECDHE_RSA_WITH_AES_128_GCM_SHA256,TLS_ECDHE_RSA_WITH_AES_256_GCM_SHA384,TLS_ECDHE_RSA_WITH_AES_128_CBC_SHA,TLS_ECDHE_RSA_WITH_AES_256_CBC_SHA,TLS_ECDHE_RSA_WITH_AES_128_CBC_SHA256,TLS_ECDHE_RSA_WITH_AES_256_CBC_SHA384,TLS_DHE_RSA_WITH_AES_128_GCM_SHA256,TLS_DHE_RSA_WITH_AES_256_GCM_SHA384,TLS_DHE_RSA_WITH_AES_128_CBC_SHA,TLS_DHE_RSA_WITH_AES_256_CBC_SHA,TLS_DHE_RSA_WITH_AES_128_CBC_SHA256,TLS_DHE_RSA_WITH_AES_256_CBC_SHA256

You achieve the same programmatically with the following code snippet:

httpClient = HttpClient.newBuilder()
  .version(HttpClient.Version.HTTP_2)
  .connectTimeout(Duration.ofSeconds(5))
  .sslContext(sslContext)
  .sslParameters(new SSLParameters(new String[]{
    "TLS_ECDHE_ECDSA_WITH_AES_128_GCM_SHA256",
    "TLS_ECDHE_ECDSA_WITH_AES_256_GCM_SHA384",
    "TLS_ECDHE_ECDSA_WITH_AES_128_CBC_SHA",
    ………
  }))
  .build();

Cleaning up

The stack creates a custom VPC and other related resources. Clean up after usage to avoid the ongoing cost of running these services. To clean up the infrastructure and the self-generated certificates, run:

./scripts/4-delete-certificates.sh
./scripts/5-deprovision-infrastructure.sh

Conclusion

mTLS in Java using KeyStore and TrustStore is a well-established approach for using client certificates to add an authentication layer. This blog highlights the four approaches that you can take to implement mTLS using Java-based Lambda functions.

Each approach addresses the separation of concerns required while implementing mTLS with additional security features. Use an approach that suits your needs, organizational security best practices, and enterprise requirements. Refer to the demo application for additional details.

For more serverless learning resources, visit Serverless Land.

Using organization IDs as principals in Lambda resource policies

Post Syndicated from Eric Johnson original https://aws.amazon.com/blogs/compute/using-organization-ids-as-principals-in-lambda-resource-policies/

This post is written by Rahul Popat, Specialist SA, Serverless and Dhiraj Mahapatro, Sr. Specialist SA, Serverless

AWS Lambda is a serverless compute service that runs your code in response to events and automatically manages the underlying compute resources for you. These events may include changes in state or an update, such as a user placing an item in a shopping cart on an ecommerce website. You can use AWS Lambda to extend other AWS services with custom logic, or create your own backend services that operate at AWS scale, performance, and security.

You may have multiple AWS accounts for your application development, but may want to keep few common functionalities in one centralized account. For example, have user authentication service in a centralized account and grant permission to other accounts to access it using AWS Lambda.

Today, AWS Lambda launches improvements to resource-based policies, which makes it easier for you to control access to a Lambda function by using the identifier of the AWS Organizations as a condition in your resource policy. The service expands the use of the resource policy to enable granting cross-account access at the organization level instead of granting explicit permissions for each individual account within an organization.

Before this release, the centralized account had to grant explicit permissions to all other AWS accounts to use the Lambda function. You had to specify each account as a principal in the resource-based policy explicitly. While that remains a viable option, managing access for individual accounts using such resource policy becomes an operational overhead when the number of accounts grows within your organization.

In this post, I walk through the details of the new condition and show you how to restrict access to only principals in your organization for accessing a Lambda function. You can also restrict access to a particular alias and version of the Lambda function with a similar approach.

Overview

For AWS Lambda function, you grant permissions using resource-based policies to specify the accounts and principals that can access it and what actions they can perform on it. Now, you can use a new condition key, aws:PrincipalOrgID, in these policies to require any principals accessing your Lambda function to be from an account (including the management account) within an organization. For example, let’s say you have a resource-based policy for a Lambda function and you want to restrict access to only principals from AWS accounts under a particular AWS Organization. To accomplish this, you can define the aws:PrincipalOrgID condition and set the value to your Organization ID in the resource-based policy. Your organization ID is what sets the access control on your Lambda function. When you use this condition, policy permissions apply when you add new accounts to this organization without requiring an update to the policy, thus reducing the operational overhead of updating the policy every time you add a new account.

Condition concepts

Before I introduce the new condition, let’s review the condition element of an IAM policy. A condition is an optional IAM policy element that you can use to specify special circumstances under which the policy grants or denies permission. A condition includes a condition key, operator, and value for the condition. There are two types of conditions: service-specific conditions and global conditions. Service-specific conditions are specific to certain actions in an AWS service. For example, the condition key ec2:InstanceType supports specific EC2 actions. Global conditions support all actions across all AWS services.

AWS:PrincipalOrgID condition key

You can use this condition key to apply a filter to the principal element of a resource-based policy. You can use any string operator, such as StringLike, with this condition and specify the AWS organization ID as its value.

Condition key Description Operators Value
aws:PrincipalOrgID Validates if the principal accessing the resource belongs to an account in your organization. All string operators Any AWS Organization ID

Restricting Lambda function access to only principals from a particular organization

Consider an example where you want to give specific IAM principals in your organization direct access to a Lambda function that logs to the Amazon CloudWatch.

Step 1 – Prerequisites

Once you have an organization and accounts setup, on the AWS Organization looks like this:

Organization accounts example

Organization accounts example

This example has two accounts in the AWS Organization, the Management Account, and the MainApp Account. Make a note of the Organization ID from the left menu. You use this to set up a resource-based policy for the Lambda function.

Step 2 – Create resource-based policy for a Lambda function that you want to restrict access to

Now you want to restrict the Lambda function’s invocation to principals from accounts that are member of your organization. To do so, write and attach a resource-based policy for the Lambda function:

{
  "Version": "2012-10-17",
  "Id": "default",
  "Statement": [
    {
      "Sid": "org-level-permission",
      "Effect": "Allow",
      "Principal": "*",
      "Action": "lambda:InvokeFunction",
      "Resource": "arn:aws:lambda:<REGION>:<ACCOUNT_ID >:function:<FUNCTION_NAME>",
      "Condition": {
        "StringEquals": {
          "aws:PrincipalOrgID": "o-sabhong3hu"
        }
      }
    }
  ]
}

In this policy, I specify Principal as *. This means that all users in the organization ‘o-sabhong3hu’ get function invocation permissions. If you specify an AWS account or role as the principal, then only that principal gets function invocation permissions, but only if they are also part of the ‘o-sabhong3hu’ organization.

Next, I add lambda:InvokeFunction as the Action and the ARN of the Lambda function as the resource to grant invoke permissions to the Lambda function. Finally, I add the new condition key aws:PrincipalOrgID and specify an Organization ID in the Condition element of the statement to make sure only the principals from the accounts in the organization can invoke the Lambda function.

You could also use the AWS Management Console to create a resource-based policy. Go to Lambda function page, click on the Configuration tab. Select Permissions from the left menu. Choose Add Permissions and fill in the required details. Scroll to the bottom and expand the Principal organization ID – optional submenu and enter your organization ID in the text box labeled as PrincipalOrgID and choose Save.

Add permissions

Add permissions

Step 3 – Testing

The Lambda function ‘LogOrganizationEvents’ is in your Management Account. You configured a resource-based policy to allow all the principals in your organization to invoke your Lambda function. Now, invoke the Lambda function from another account within your organization.

Sign in to the MainApp Account, which is another member account in the same organization. Open AWS CloudShell from the AWS Management Console. Invoke the Lambda function ‘LogOrganizationEvents’ from the terminal, as shown below. You receive the response status code of 200, which means success. Learn more on how to invoke Lambda function from AWS CLI.

Console example of access

Console example of access

Conclusion

You can now use the aws:PrincipalOrgID condition key in your resource-based policies to restrict access more easily to IAM principals only from accounts within an AWS Organization. For more information about this global condition key and policy examples using aws:PrincipalOrgID, read the IAM documentation.

If you have questions about or suggestions for this solution, start a new thread on the AWS Lambda or contact AWS Support.

For more information, visit Serverless Land.

Save Cost and Improve Lambda Application Performance with Proactive Insights from Amazon DevOps Guru

Post Syndicated from Venkata Moparthi original https://aws.amazon.com/blogs/devops/save-cost-and-improve-lambda-application-performance-with-proactive-insights-from-amazon-devops-guru/

AWS customers, regardless of size and market segment, constantly seek to improve application performance while reducing operational costs. Today, Amazon DevOps Guru generates proactive insights that enable you to reduce the cost and improve the performance of your AWS Lambda application. By proactively analyzing your application and making these cost-saving and/or performance-improving recommendations, DevOps Guru frees up your operations team to focus on other value-adding activities.

DevOps Guru is a machine learning (ML)-powered service that helps you effectively monitor your application by ingesting application metrics, learning your application’s behavior over time, and then detecting operational anomalies. Once an anomaly is detected, DevOps Guru generates insights that include specific recommendations of how to fix the underlying problem.

To make sure that AWS customers remain ahead of potential issues, DevOps Guru detects some applications issues proactively and provides recommendations that let customers correct them before customer-impacting events actually occur. These Proactive Insights are created by analyzing operational data and application metrics with ML algorithms that can identify early signals that are linked with future operational issues.

In this post, we’ll review a scenario in which the provisioned concurrency capacity for a Lambda function was set too low. This put the customer at risk of dropped requests (throttling), which degrade application performance and deliver poor user experience during traffic spikes.

Prerequisites

In the scenario under review, we have an account with DevOps Guru set up to monitor a Lambda-based application stack. Enabling DevOps Guru and setting it up to monitor a Lambda function is straightforward, and you can refer to this post to see how this is done. For the Lambda function in this account, we have set the provisioned concurrency set too low. This Lambda documentation page covers how to estimate the appropriate concurrency levels for your function.

Architecture Overview

The reference architecture for our scenario can be seen in the following image.

In this simple serverless architecture, the Lambda-based application vends the metrics to Amazon CloudWatch. Then, DevOps Guru ingests the metrics from CloudWatch for analysis.

Architecture diagram explained in post.

By default, DevOps Guru ingests vended metrics via CloudWatch at no cost to customers.

Baselining

The first time that you enable and configure DevOps Guru to monitor resources, it starts baselining your resources to determine your application’s normal behavior. Unlike rule-based alarming systems, DevOps Guru utilizes dynamic thresholds that are controlled by ML algorithms and calibrated to the specifics of your application to reduce noise. For a simple serverless stack, baselining can be completed in two hours. However, in a production environment baselining can take up to 24-hours depending upon the number of resources being monitored. After initial baselining, analysis becomes continuous and baselining is no longer required.

Proactive Insight Generation

Once baselining is complete, DevOps Guru analyzes the baselined operational and generates insights where present. These insights can be found on the Insights page of the DevOps Guru console. To view the available insights, navigate to Insights, and select the Proactive Insights or Reactive Insights. In this scenario, we’re reviewing a Proactive Insight.

Devops guru Insights page. Four proactive insights with status of ongoing

On this tab, note that the LambdaAuthorizer -1HQG1OD function has a concurrency spillover invocation. For a given Lambda function, concurrency spillover is invoked when the number of concurrent requests reaches the provisioned concurrency limit. When this occurs, Lambda either begins to run on unreserved concurrency (leading to cold starts) or rejects additional incoming requests, depending on your function scaling configuration.

By selecting the relevant insight from the list, we open the insight detail page. The insight overview card provides an overview of the insight, with high-level information such as insight description, severity, status, and the number of affected applications as shown in the following screenshot.

Insight detail page. Shows insight overview, previously explained in post.

The metrics card presents a graph plotted against time. In this case, provisioned concurrency invocation, which toggles from 0 to 1 when concurrency spillover occurs, was triggered because the Lambda function received more concurrent requests than were provisioned for.

Metric card with graph plotted against time.

The relevant events card is useful in situations where more than one application is affected, or when the initial event triggers additional events. This card plots all of the events from different related applications on a time axis. Therefore, we can pinpoint which event triggered the chain of events.

Relevent events card, previously explained in post.

Recommendations

The recommendation section of the insight page provides specific and actionable guidance on what actions customers should take to fix the underlying cause of the issue. In this case, DevOps Guru recommends that the customer set the provisioned concurrency to 264 to keep the utilization balanced at 65%. Providing such specific guidance takes away any ambiguity and significantly reduces troubleshooting time.

Recommendations section previously explained in post.

Other Lambda-related Proactive Insights

While this scenario alerts customers to an issue that impacts application performance, DevOps Guru also provides alerts for cost-optimization issues. Some additional cost and performance-related issues that DevOps Guru identifies include:

  • Lambda Provisioned with No Autoscaling, which is triggered when autoscaling isn’t enabled, thereby putting the application at risk of degraded performance when requests are throttled during a traffic spike.
  • Low Lambda Provision Concurrency Utilization, which is triggered when provisioned concurrency is consistently higher than required, driving unnecessary cloud spend.
  • Over-provisioned Amazon DynamoDB Stream Shards, which is triggered when provisioned Amazon DynamoDB stream shards is consistently higher than required, driving unnecessary cloud spend.

DevOps Guru continues to expand its library of proactive insight use cases to deliver cost and performance improvements continuously to AWS customers.

Conclusion

As seen in the example above, DevOps Guru can proactively detect issues with your Lambda applications, tie these issues to related events, and provide precise remedial actions using its pre-trained ML models. As a customer, you can start leveraging these capabilities to improve the performance of your Lambda applications by simply enabling DevOps Guru—a process that requires minimal configuration and no previous ML expertise.

Start using DevOps Guru to monitor your Lambda Applications today!

About the authors

Mohit Gadkari

Mohit Gadkari is a Solutions Architect at Amazon Web Services (AWS) supporting SMB customers. He has been professionally using AWS since 2015 specializing in DevOps and Cloud Security and currently he is using this experience to help customers navigate the cloud.

Venkata Moparthi

Venkata Moparthi is a Cloud Infrastructure Architect at Amazon Web Services. He helps customers on their cloud adoption journey. He is passionate about technology and enjoys collaborating with customers architecting and implementing highly scalable and secure solutions.