Tag Archives: Best practices

Implement an early feedback loop with AWS developer tools to shift security left

Post Syndicated from Barry Conway original https://aws.amazon.com/blogs/security/implement-an-early-feedback-loop-with-aws-developer-tools-to-shift-security-left/

Early-feedback loops exist to provide developers with ongoing feedback through automated checks. This enables developers to take early remedial action while increasing the efficiency of the code review process and, in turn, their productivity.

Early-feedback loops help provide confidence to reviewers that fundamental security and compliance requirements were validated before review. As part of this process, common expectations of code standards and quality can be established, while shifting governance mechanisms to the left.

In this post, we will show you how to use AWS developer tools to implement a shift-left approach to security that empowers your developers with early feedback loops within their development practices. You will use AWS CodeCommit to securely host Git repositories, AWS CodePipeline to automate continuous delivery pipelines, AWS CodeBuild to build and test code, and Amazon CodeGuru Reviewer to detect potential code defects.

Why the shift-left approach is important

Developers today are an integral part of organizations, building and maintaining the most critical customer-facing applications. Developers must have the knowledge, tools, and processes in place to help them identify potential security issues before they release a product to production.

This is why the shift-left approach is important. Shift left is the process of checking for vulnerabilities and issues in the earlier stages of software development. By following the shift-left process (which should be part of a wider application security review and threat modelling process), software teams can help prevent undetected security issues when they build an application. The modern DevSecOps workflow continues to shift left towards the developer and their practices with the aim to achieve the following:

  • Drive accountability among developers for the security of their code
  • Empower development teams to remediate issues up front and at their own pace
  • Improve risk management by enabling early visibility of potential security issues through early feedback loops

You can use AWS developer tools to help provide this continual early feedback for developers upon each commit of code.

Solution prerequisites

To follow along with this solution, make sure that you have the following prerequisites in place:

Make sure that you have a general working knowledge of the listed services and DevOps practices.

Solution overview

The following diagram illustrates the architecture of the solution.

Figure 1: Solution overview

Figure 1: Solution overview

We will show you how to set up a continuous integration and continuous delivery (CI/CD) pipeline by using AWS developer tools—CodeCommit, CodePipeline, CodeBuild, and CodeGuru—that you will integrate with the code repository to detect code security vulnerabilities. As shown in Figure 1, the solution has the following steps:

  1. The developer commits the new branch into the code repository.
  2. The developer creates a pull request to the main branch.
  3. Pull requests initiate two jobs: an Amazon CodeGuru Reviewer code scan and a CodeBuild job.
    1. CodeGuru Reviewer uses program analysis and machine learning to help detect potential defects in your Java and Python code, and provides recommendations to improve the code. CodeGuru Reviewer helps detect security vulnerabilities, secrets, resource leaks, concurrency issues, incorrect input validation, and deviation from best practices for using AWS APIs and SDKs.
    2. You can configure the CodeBuild deployment with third-party tools, such as Bandit for Python to help detect security issues in your Python code.
  4. CodeGuru Reviewer or CodeBuild writes back the findings of the code scans to the pull request to provide a single common place for developers to review the findings that are relevant to their specific code updates.

The following table presents some other tools that you can integrate into the early-feedback toolchain, depending on the type of code or artefacts that you are evaluating:

Early feedback – security tools Usage License
cfn-guard , cfn-nag , cfn-lint Infrastructure linting and validation cfn-guard license, cfn-nag license, cfn-lint license
CodeGuru, Bandit Python Bandit license
CodeGuru Java
npm-audit, Dependabot npm libraries Dependabot license

When you deploy the solution in your AWS account, you can review how Bandit for Python has been built into the deployment pipeline by using AWS CodeBuild with a configured buildspec file, as shown in Figure 2. You can implement the other tools in the table by using a similar approach.

Figure 2: Bandit configured in CodeBuild

Figure 2: Bandit configured in CodeBuild

Walkthrough

To deploy the solution, you will complete the following steps:

  1. Deploy the solution by using a CloudFormation template
  2. Associate CodeGuru with a code repository
  3. Create a pull request to the code repository
  4. Review the code scan results in the pull request and address the findings

Deploy the solution

The first step is to deploy the required resources into your AWS environment by using CloudFormation.

To deploy the solution

  1. Choose the following Launch Stack button to deploy the solution’s CloudFormation template:

    Select this image to open a link that starts building the CloudFormation stack

    The solution deploys in the AWS US East (N. Virginia) Region (us-east-1) by default because each service listed in the Prerequisites section is available in this Region. To deploy the solution in a different Region, use the Region selector in the console navigation bar and make sure that the services required for this walkthrough are supported in your newly selected Region. For service availability by Region, see AWS Services by Region.

  2. On the Quick Create Stack screen, do the following:
    1. Leave the provided parameter defaults in place.
    2. Scroll to the bottom, and in the Capabilities section, select I acknowledge that AWS CloudFormation might create IAM resources with custom names.
    3. Choose Create Stack.
  3. When the CloudFormation template has completed, open the AWS Cloud9 console.
  4. In the Environments table, for the provisioned shift-left-blog-cloud9-ide environment, choose Open, as shown in Figure 3.
    Figure 3: Cloud9 environments

    Figure 3: Cloud9 environments

  5. The provisioned Cloud9 environment opens in a new tab. Wait for Cloud9 to initialize the two sample code repositories: shift-left-sample-app-java and shift-left-sample-app-python, as shown in Figure 4. For this post, you will work only with the Python sample repository shift-left-sample-app-python, but the procedures we outline will also work for the Java repository.
    Figure 4: Cloud9 IDE

    Figure 4: Cloud9 IDE

Associate CodeGuru Reviewer with a code repository

The next step is to associate the Python code repository with CodeGuru Reviewer. After you associate the repository, CodeGuru Reviewer analyzes and comments on issues that it finds when you create a pull request.

To associate CodeGuru Reviewer with a repository

  1. Open the CodeGuru console, and in the left navigation pane, under Reviewer, choose Repositories.
  2. In the Repositories section, choose Associate repository and run analysis.
  3. In the Associate repository section, do the following:
    1. For Select source provider, select AWS CodeCommit.
    2. For Repository location,select shift-left-sample-app-python.
  4. In the Run a repository analysis section, do the following, as shown in Figure 5:
    1. For Source branch, select main.
    2. For Code review name – optional, enter a name.
    3. For Tags – optional, leave the default settings.
    4. Choose Associate repository and run analysis.
      Figure 5: CodeGuru repository configuration

      Figure 5: CodeGuru repository configuration

  5. CodeGuru initiates the Full repository analysis and the status is Pending, as shown in Figure 6. The full analysis takes about 5 minutes to complete. Wait for the status to change from Pending to Completed.
    Figure 6: CodeGuru full analysis pending

    Figure 6: CodeGuru full analysis pending

Create a pull request

The next step is to create a new branch and to push sample code to the repository by creating a pull request so that the code scan can be initiated by CodeGuru Reviewer and the CodeBuild job.

To create a new branch

  1. In the Cloud9 IDE, locate the terminal and create a new branch by running the following commands.
    cd ~/environment/shift-left-sample-app-python
    git checkout -b python-test

  2. Confirm that you are working from the new branch, which will be highlighted in the Cloud9 IDE terminal, as shown in Figure 7.
    git branch -v

    Figure 7: Cloud9 IDE terminal

    Figure 7: Cloud9 IDE terminal

To create a new file and push it to the code repository

  1. Create a new file called sample.py.
    touch sample.py

  2. Copy the following sample code, paste it into the sample.py file, and save the changes, as shown in Figure 8.
    import requests
    
    data = requests.get("https://www.example.org/", verify = False)
    print(data.status_code)

    Figure 8: Cloud9 IDE noncompliant code

    Figure 8: Cloud9 IDE noncompliant code

  3. Commit the changes to the repository.
    git status
    git add -A
    git commit -m "shift left blog python sample app update"

    Note: if you receive a message to set your name and email address, you can ignore it because Git will automatically set these for you, and the Git commit will complete successfully.

  4. Push the changes to the code repository, as shown in Figure 9.
    git push origin python-test

    Figure 9: Git push

    Figure 9: Git push

To create a new pull request

  1. Open the CodeCommit console and select the code repository called shift-left-sample-app-python.
  2. From the Branches dropdown, select the new branch that you created and pushed, as shown in Figure 10.
    Figure 10: CodeCommit branch selection

    Figure 10: CodeCommit branch selection

  3. In your new branch, select the file sample.py, confirm that the file has the changes that you made, and then choose Create pull request, as shown in Figure 11.
    Figure 11: CodeCommit pull request

    Figure 11: CodeCommit pull request

    A notification appears stating that the new code updates can be merged.

  4. In the Source dropdown, choose the new branch python-test. In the Destination dropdown, choose the main branch where you intend to merge your code changes when the pull request is closed.
  5. To have CodeCommit run a comparison between the main branch and your new branch python-test, choose Compare. To see the differences between the two branches, choose the Changes tab at the bottom of the page. CodeCommit also assesses whether the two branches can be merged automatically when the pull request is closed.
  6. When you’re satisfied with the comparison results for the pull request, enter a Title and an optional Description, and then choose Create pull request. Your pull request appears in the list of pull requests for the CodeCommit repository, as shown in Figure 12.
    Figure 12: Pull request

    Figure 12: Pull request

The creation of this pull request has automatically started two separate code scans. The first is a CodeGuru incremental code review and the second uses CodeBuild, which utilizes Bandit to perform a security code scan of the Python code.

Review code scan results and resolve detected security vulnerabilities

The next step is to review the code scan results to identify security vulnerabilities and the recommendations on how to fix them.

To review the code scan results

  1. Open the CodeGuru console, and in the left navigation pane, under Reviewer, select Code reviews.
  2. On the Incremental code reviews tab, make sure that you see a new code review item created for the preceding pull request.
    Figure 13: CodeGuru Code review

    Figure 13: CodeGuru Code review

  3. After a few minutes, when CodeGuru completes the incremental analysis, choose the code review to review the CodeGuru recommendations on the pull request. Figure 14 shows the CodeGuru recommendations for our example.
    Figure 14: CodeGuru recommendations

    Figure 14: CodeGuru recommendations

  4. Open the CodeBuild console and select the CodeBuild job called shift-left-blog-pr-Python. In our example, this job should be in a Failed state.
  5. Open the CodeBuild run, and under the Build history tab, select the CodeBuild job, which is in Failed state. Under the Build Logs tab, scroll down until you see the following errors in the logs. Note that the severity of the finding is High, which is why the CodeBuild job failed. You can review the Bandit scanning options in the Bandit documentation.
    Test results:
    >> Issue: [B501:request_with_no_cert_validation] Call to requests with verify=False disabling SSL certificate checks, security issue.
       Severity: High   Confidence: High
       CWE: CWE-295 (https://cwe.mitre.org/data/definitions/295.html)
       More Info: https://bandit.readthedocs.io/en/1.7.5/plugins/b501_request_with_no_cert_validation.html
       Location: sample.py:3:7
    
    2   
    3   data = requests.get("https://www.example.org/", verify = False)
    4   print(data.status_code)

  6. Navigate to the CodeCommit console, and on the Activity tab of the pull request, review the CodeGuru recommendations. You can also review the results of the CodeBuild jobs that Bandit performed, as shown in Figure 15.
    Figure 15: CodeGuru recommendations and CodeBuild logs

    Figure 15: CodeGuru recommendations and CodeBuild logs

This demonstrates how developers can directly link the relevant information relating to security code scans with their code development and associated pull requests, hence shifting to the left the required security awareness for developers.

To resolve the detected security vulnerabilities

  1. In the Cloud9 IDE, navigate to the file sample.py in the Python sample repository, as shown in Figure 16.
    Figure 16: Cloud9 IDE sample.py

    Figure 16: Cloud9 IDE sample.py

  2. Copy the following code and paste it in the sample.py file, overwriting the existing code. Save the update.
    import requests
    
    data = requests.get("https://www.example.org", timeout=5)
    print(data.status_code)

  3. Commit the changes by running the following commands.
    git status
    git add -A
    git commit -m "shift left python sample.py resolve security errors"
    git push origin python-test

  4. Open the CodeCommit console and choose the Activity tab on the pull request that you created earlier. You will see a banner indicating that the pull request was updated. You will also see new comments indicating that new code scans using CodeGuru and CodeBuild were initiated for the new pull request update.
  5. In the CodeGuru console, on the Incremental code reviews page, check that a new code scan has begun. When the scans are finished, review the results in the CodeGuru console and the CodeBuild build logs, as described previously. The previously detected security vulnerability should now be resolved.
  6. In the CodeCommit console, on the Activity tab, under Activity history, review the comments to verify that each of the code scans has a status of Passing, as shown in Figure 17.
    Figure 17: CodeCommit activity history

    Figure 17: CodeCommit activity history

  7. Now that the security issue has been resolved, merge the pull request into the main branch of the code repository. Choose Merge, and under Merge strategy, select Fast Forward merge.

AWS account clean-up

Clean up the resources created by this solution to avoid incurring future charges.

To clean up your account

  1. Start by deleting the CloudFormation stacks for the Java and Python sample applications that you deployed. In the CloudFormation console, in the Stacks section, select one of these stacks and choose Delete; then select the other stack and choose Delete.
    Figure 18: Delete repository stack

    Figure 18: Delete repository stack

  2. To initiate deletion of the Cloud9 CloudFormation stack, select it and choose Delete.
  3. Open the Amazon S3 console, and in the search box, enter shift-left to search for the S3 bucket that CodePipeline used.
    Figure 19: Select CodePipeline S3 bucket

    Figure 19: Select CodePipeline S3 bucket

  4. Select the S3 bucket, select all of the object folders in the bucket, and choose Delete
    Figure 20: Select CodePipeline S3 objects

    Figure 20: Select CodePipeline S3 objects

  5. To confirm deletion of the objects, in the section Permanently delete objects?, enter permanently delete, and then choose Delete objects. A banner message that states Successfully deleted objects appears at the top confirming the object deletion.
  6. Navigate back to the CloudFormation console, select the stack named shift-left-blog, and choose Delete.

Conclusion

In this blog post, we showed you how to implement a solution that enables early feedback on code development through status comments in the CodeCommit pull request activity tab by using Amazon CodeGuru Reviewer and CodeBuild to perform automated code security scans on the creation of a code repository pull request.

We configured CodeBuild with Bandit for Python to demonstrate how you can integrate third-party or open-source tools into the development cycle. You can use this approach to integrate other tools into the workflow.

Shifting security left early in the development cycle can help you identify potential security issues earlier and empower teams to remediate issues earlier, helping to prevent the need to refactor code towards the end of a build.

This solution provides a simple method that you can use to view and understand potential security issues with your newly developed code and thus enhances your awareness of the security requirements within your organization.

It’s simple to get started. Sign up for an AWS account, deploy the provided CloudFormation template through the Launch Stack button, commit your code, and start scanning for vulnerabilities.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on AWS re:Post or contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Barry Conway

Barry Conway

Barry is an Enterprise Solutions Architect with years of experience in the technology industry, bridging the gap between business and technology. Barry has helped banking, manufacturing, logistics, and retail organizations realize their business goals.

Author

Deenadayaalan Thirugnanasambandam

Deenadayaalan is a Senior Practice manager at AWS. He provides prescriptive architectural guidance and consulting to help accelerate customers’ adoption of AWS.

Balamurugan Kumaran

Balamurugan Kumaran

Balamurugan is a Senior Cloud Architect at AWS. Over the years, Bala has architected and implemented highly available, scalable, and secure applications using AWS services for various enterprise customers.

Nitin Kumar

Nitin Kumar

Nitin is a Senior Cloud Architect at AWS. He plays a pivotal role in driving organizational success by harnessing the power of technology. With a focus on enabling innovation through architectural guidance and consulting, he empowers customers to excel on the AWS Cloud. Outside of work, Nitin dedicates his time to crafting IoT devices for reef tanks.

Power enterprise-grade Data Vaults with Amazon Redshift – Part 1

Post Syndicated from Asser Moustafa original https://aws.amazon.com/blogs/big-data/power-enterprise-grade-data-vaults-with-amazon-redshift-part-1/

Amazon Redshift is a popular cloud data warehouse, offering a fully managed cloud-based service that seamlessly integrates with an organization’s Amazon Simple Storage Service (Amazon S3) data lake, real-time streams, machine learning (ML) workflows, transactional workflows, and much more—all while providing up to 7.9x better price-performance than other cloud data warehouses.

As with all AWS services, Amazon Redshift is a customer-obsessed service that recognizes there isn’t a one-size-fits-all for customers when it comes to data models, which is why Amazon Redshift supports multiple data models such as Star Schemas, Snowflake Schemas and Data Vault. This post discusses best practices for designing enterprise-grade Data Vaults of varying scale using Amazon Redshift; the second post in this two-part series discusses the most pressing needs when designing an enterprise-grade Data Vault and how those needs are addressed by Amazon Redshift.

Whether it’s a desire to easily retain data lineage directly within the data warehouse, establish a source-system agnostic data model within the data warehouse, or more easily comply with GDPR regulations, customers that implement a Data Vault model will benefit from this post’s discussion of considerations, best practices, and Amazon Redshift features relevant to the building of enterprise-grade Data Vaults. Building a starter version of anything can often be straightforward, but building something with enterprise-grade scale, security, resiliency, and performance typically requires knowledge of and adherence to battle-tested best practices, and using the right tools and features in the right scenario.

Data Vault overview

Let’s first briefly review the core Data Vault premise and concepts. Data models provide a framework for how the data in a data warehouse should be organized into database tables. Amazon Redshift supports a number of data models, and some of the most popular data models include STAR schemas and Data Vault.

Data Vault is not only a modeling methodology, it’s also an opinionated framework that tells you how to solve certain problems in your data ecosystem. An opinionated framework provides a set of guidelines and conventions that developers are expected to follow, rather than leaving all decisions up to the developer. You can compare this with what big enterprise frameworks like Spring or Micronauts do when developing applications at enterprise scale. This is incredibly helpful especially on large data warehouse projects, because it structures your extract, load, and transform (ELT) pipeline and clearly tells you how to solve certain problems within the data and pipeline contexts. This also allows for a high degree of automation.

Data Vault 2.0 allows for the following:

  • Agile data warehouse development
  • Parallel data ingestion
  • A scalable approach to handle multiple data sources even on the same entity
  • A high level of automation
  • Historization
  • Full lineage support

However, Data Vault 2.0 also comes with costs, and there are use cases where it’s not a good fit, such as the following:

  • You only have a few data sources with no related or overlapping data (for example, a bank with a single core system)
  • You have simple reporting with infrequent changes
  • You have limited resources and knowledge of Data Vault

Data Vault typically organizes an organization’s data into a pipeline of four layers: staging, raw, business, and presentation. The staging layer represents data intake and light data transformations and enhancements that occur before the data comes to its more permanent resting place, the raw Data Vault (RDV).

The RDV holds the historized copy of all of the data from multiple source systems. It is referred to as raw because no filters or business transformations have occurred at this point except for storing the data in source system independent targets. The RDV organizes data into three key types of tables:

  • Hubs – This type of table represents a core business entity such as a customer. Each record in a hub table is married with metadata that identifies the record’s creation time, originating source system, and unique business key.
  • Links – This type of table defines a relationship between two or more hubs—for example, how the customer hub and order hub are to be joined.
  • Satellites – This type of table records the historized reference data about either hubs or links, such as product_info and customer_info

The RDV is used to feed data into the business Data Vault (BDV), which is responsible for reorganizing, denormalizing, and aggregating data for optimized consumption by the presentation mart. The presentation marts, also known as the data mart layer, further reorganizes the data for optimized consumption by downstream clients such as business dashboards. The presentation marts may, for example, reorganize data into a STAR schema.

For a more detailed overview of Data Vault along with a discussion of its applicability in the context of very interesting use cases, refer to the following:

How does Data Vault fit into a modern data architecture?

Currently, the lake house paradigm is becoming a major pattern in data warehouse design, even as part of a data mesh architecture. This follows the pattern of data lakes getting closer to what a data warehouse can do and vice versa. To compete with the flexibility of a data lake, Data Vault is a good choice. This way, the data warehouse doesn’t become a bottleneck and you can achieve similar agility, flexibility, scalability, and adaptability when ingestion and onboarding new data.

Platform flexibility

In this section, we discuss some recommended Redshift configurations for Data Vaults of varying scale. As mentioned earlier, the layers within a Data Vault platform are well known. We typically see a flow from the staging layer to the RDV, BDV, and finally presentation mart.

The Amazon Redshift is highly flexible in supporting both modest and large-scale Data Vaults, offering features like the following:

Modest vs. large-scale Data Vaults

Amazon Redshift is flexible in how you decide to structure these layers. For modest data vaults, a single Redshift warehouse with one database with multiple schemas will work just fine.

For large data vaults with more complex transformations, we would look at multiple warehouses, each with their own schema of mastered data representing one or more layer. The reason for using multiple warehouses is to take advantage of the Amazon Redshift architecture’s flexibility for implementing large-scale data vault implementations, such as using Redshift RA3 nodes and Redshift Serverless for separating the compute from the data storage layer and using Redshift data sharing to share the data between different Redshift warehouses. This enables you to scale the compute capacity independently at each layer depending on the processing complexity. The staging layer, for example, can be a layer within your data lake (Amazon S3 storage) or a schema within a Redshift database.

Using Amazon Aurora zero-ETL integrations with Amazon Redshift, you can create a data vault implementation with a staging layer in an Amazon Aurora database that will take care of real-time transaction processing and move the data to Amazon Redshift automatically for further processing in the Data Vault implementation without creating any complex ETL pipelines. This way, you can use Amazon Aurora for transactions and Amazon Redshift for analytics. Compute resources are isolated for the same data, and you’re using the most efficient tools to process it.

Large-scale Data Vaults

For larger Data Vaults platforms, concurrency and compute power become important to process both the loading of data and any business transformations. Amazon Redshift offers flexibility to increase compute capacity both horizontally via concurrency scaling and vertically via cluster resize and also via different architectures for each Data Vault layer.

Staging layer

You can create a data warehouse for the staging layer and perform hard business rules processing here, including calculation of hash keys, hash diffs, and addition of technical metadata columns. If data is not loaded 24/7, consider either pause/resume or a Redshift Serverless workgroup.

Raw Data Vault layer

For raw Data Vault (RDV), it’s recommended to either create one Redshift warehouse for the whole RDV or one Redshift warehouse for one or more subject areas within the RDV. For example, if the volume of data and number of normalized tables within the RDV for a particular subject area is large (either the raw data layer has so many tables that it runs out of maximum table limit on Amazon Redshift or the advantage of workload isolation within a single Redshift warehouse outweighs the overhead of performance and management), this subject area within the RDV can be run and mastered on its own Redshift warehouse.

The RDV is typically loaded 24/7 so a provisioned Redshift data warehouse may be most suitable here to take advantage of reserved instance pricing.

Business Data Vault layer

For creating a data warehouse for the business Data Vault (BDV) layer, this could be larger in size than the previous data warehouses due to the nature of the BDV processing, typically denormalization of data from a large number of source RDV tables.

Some customers run their BDV processing once a day, so a pause/resume window for Redshift provisioned cluster may be cost beneficial here. You can also run BDV processing on an Amazon Redshift Serverless warehouse which will automatically pause when workloads complete and resume when workloads start processing again.

Presentation Data Mart layer

For creating Redshift (provisioned or serverless) warehouses for one or more data marts, the schemas within these marts typically contain views or materialized views, so a Redshift data share will be set up between the data marts and the previous layers.

We need to ensure there is enough concurrency to cope with the increased read traffic at this level. This is achieved via multiple read only warehouses with a data share or the use of concurrency scaling to auto scale.

Example architectures

The following diagram illustrates an example platform for a modest Data Vault model.

The following diagram illustrates the architecture for a large-scale Data Vault model.

Data Vault data model guiding principles

In this section, we discuss some recommended design principles for joining and filtering table access within a Data Vault implementation. These guiding principles address different combinations of entity type access, but should be tested for suitability with each client’s particular use case.

Let’s begin with a brief refresher of table distribution styles in Amazon Redshift. There are four ways that a table’s data can be distributed among the different compute nodes in a Redshift cluster: ALL, KEY, EVEN, and AUTO.

The ALL distribution style ensures that a full copy of the table is maintained on each compute node to eliminate the need for inter-node network communication during workload runs. This distribution style is ideal for tables that are relatively small in size (such as fewer than 5 million rows) and don’t exhibit frequent changes.

The KEY distribution style uses a hash-based approach to persisting a table’s rows in the cluster. A distribution key column is defined to be one of the columns in the row, and the value of that column is hashed to determine on which compute node the row will be persisted. The current generation RA3 node type is built on the AWS Nitro System with managed storage that uses high performance SSDs for your hot data and Amazon S3 for your cold data, providing ease of use, cost-effective storage, and fast query performance. Managed storage means this mapping of row to compute node is more in terms of metadata and compute node ownership rather than the actual persistence. This distribution style is ideal for large tables that have well-known and frequent join patterns on the distribution key column.

The EVEN distribution style uses a round-robin approach to locating a table’s row. Simply put, table rows are cycled through the different compute nodes and when the last compute node in the cluster is reached, the cycle begins again with the next row being persisted to the first compute node in the cluster. This distribution style is ideal for large tables that exhibit frequent table scans.

Finally, the default table distribution style in Amazon Redshift is AUTO, which empowers Amazon Redshift to monitor how a table is used and change the table’s distribution style at any point in the table’s lifecycle for greater performance with workloads. However, you are also empowered to explicitly state a particular distribution style at any point in time if you have a good understanding of how the table will be used by workloads.

Hub and hub satellites

Hub and hub satellites are often joined together, so it’s best to co-locate these datasets based on the primary key of the hub, which will also be part of the compound key of each satellite. As mentioned earlier, for smaller volumes (typically fewer than 5–7 million rows) use the ALL distribution style and for larger volumes, use the KEY distribution style (with the _PK column as the distribution KEY column).

Link and link satellites

Link and link satellites are often joined together, so it’s best to co-locate these datasets based on the primary key of the link, which will also be part of the compound key of each link satellite. These typically involve larger data volumes, so look at a KEY distribution style (with the _PK column as the distribution KEY column).

Point in time and satellites

You may decide to denormalize key satellite attributes by adding them to point in time (PIT) tables with the goal of reducing or eliminating runtime joins. Because denormalization of data helps reduce or eliminate the need for runtime joins, denormalized PIT tables can be defined with an EVEN distribution style to optimize table scans.

However, if you decide not to denormalize, then smaller volumes should use the ALL distribution style and larger volumes should use the KEY distribution style (with the _PK column as the distribution KEY column). Also, be sure to define the business key column as a sort key on the PIT table for optimized filtering.

Bridge and link satellites

Similar to PIT tables, you may decide to denormalize key satellite attributes by adding them to bridge tables with the goal of reducing or eliminating runtime joins. Although denormalization of data helps reduce or eliminate the need for runtime joins, denormalized bridge tables are still typically larger in data volume and involved frequent joins, so the KEY distribution style (with the _PK column as the distribution KEY column) would be the recommended distribution style. Also, be sure to define the bridge of the dominant business key columns as sort keys for optimized filtering.

KPI and reporting

KPI and reporting tables are designed to meet the specific needs of each customer, so flexibility on their structure is key here. These are often standalone tables that exhibit multiple types of interactions, so the EVEN distribution style may be the best table distribution style to evenly spread the scan workloads.

Be sure to choose a sort key that is based on common WHERE clauses such as a date[time] element or a common business key. In addition, a time series table can be created for very large datasets that are always sliced on a time attribute to optimize workloads that typically interact with one slice of time. We discuss this subject in greater detail later in the post.

Non-functional design principles

In this section, we discuss potential additional data dimensions that are often created and married with business data to satisfy non-functional requirements. In the physical data model, these additional data dimensions take the form of technical columns added to each row to enable tracking of non-functional requirements. Many of these technical columns will be populated by the Data Vault framework. The following table lists some of the common technical columns, but you can extend the list as needed.

Column Name Applies to Table Description
LOAD_DTS All A timestamp recording of when this row was inserted. This is a primary key column for historized targets (links, satellites, reference), and a non-primary key column for transactional links and hubs.
BATCH_ID All A unique process ID identifying the run of the ETL code that populated the row.
JOB_NAME All The process name from the ETL framework. This may be a sub-process within a larger process.
SOURCE_SYSTEM_CD All The system from which this data was discovered.
HASH_DIFF Satellite A method in Data Vault of performing change data capture (CDC) changes.
RECORD_ID Satellite
Link
Reference
A unique identifier captured by the code framework for each row.
EFFECTIVE_DTS Link Business effective dates to record the business validity of the row. It’s set to the LOAD_DTS if no business date is present or needed.
DQ_AUDIT Satellite
Link
Reference
Warnings and errors found during staging for this row, tied to the RECORD_ID.

Advanced optimizations and guidelines

In this section, we discuss potential optimizations that can be deployed at the start or later on in the lifecycle of the Data Vault implementation.

Time series tables

Let’s begin with a brief refresher on time series tables as a pattern. Time series tables involve taking a large table and segmenting it into multiple identical tables that hold a time-bound portion of the rows in the original table. One common scenario is to divide a monolithic sales table into monthly or annual versions of the sales table (such as sales_jan,sales_feb, and so on). For example, let’s assume we want to maintain data for a rolling time period using a series of tables, as the following diagram illustrates.

With each new calendar quarter, we create a new table to hold the data for the new quarter and drop the oldest table in the series. Furthermore, if the table rows arrive in a naturally sorted order (such as sales date), then no work is needed to sort the table data, resulting in skipping the expensive VACUUM SORT operation on table.

Time series tables can help significantly optimize workloads that often need to scan these large tables but within a certain time range. Furthermore, by segmenting the data across tables that represent calendar quarters, we are able to drop aged data with a single DROP command. Had we tried to perform the same DELETE operation on a monolithic table design using the DELETE command, for example, it would have been a more expensive deletion operation that would have left the table in a suboptimal state requiring defragmentation and also saves to run a subsequent VACUUM process to reclaim space.

Should a workload ever need to query against the entire time range, you can use standard or materialized views using a UNION ALL operation within Amazon Redshift to easily stitch all the component tables back into the unified dataset. Materialized views can also be used to abstract the table segmentation from downstream users.

In the context of Data Vault, time series tables can be useful for archiving rows within satellites, PIT, and bridge tables that aren’t used often. Time series tables can then be used to distribute the remaining hot rows (rows that are either recently added or referenced often) with more aggressive table properties.

Conclusion

In this post, we discussed a number of areas ripe for optimization and automation to successfully implement a Data Vault 2.0 system at scale and the Amazon Redshift capabilities that you can use to satisfy the related requirements. There are many more Amazon Redshift capabilities and features that will surely come in handy, and we strongly encourage current and prospective customers to reach out to us or other AWS colleagues to delve deeper into Data Vault with Amazon Redshift.


About the Authors

Asser Moustafa is a Principal Analytics Specialist Solutions Architect at AWS based out of Dallas, Texas. He advises customers globally on their Amazon Redshift and data lake architectures, migrations, and visions—at all stages of the data ecosystem lifecycle—starting from the POC stage to actual production deployment and post-production growth.

Philipp Klose is a Global Solutions Architect at AWS based in Munich. He works with enterprise FSI customers and helps them solve business problems by architecting serverless platforms. In this free time, Philipp spends time with his family and enjoys every geek hobby possible.

Saman Irfan is a Specialist Solutions Architect at Amazon Web Services. She focuses on helping customers across various industries build scalable and high-performant analytics solutions. Outside of work, she enjoys spending time with her family, watching TV series, and learning new technologies.

Power enterprise-grade Data Vaults with Amazon Redshift – Part 2

Post Syndicated from Asser Moustafa original https://aws.amazon.com/blogs/big-data/power-enterprise-grade-data-vaults-with-amazon-redshift-part-2/

Amazon Redshift is a popular cloud data warehouse, offering a fully managed cloud-based service that seamlessly integrates with an organization’s Amazon Simple Storage Service (Amazon S3) data lake, real-time streams, machine learning (ML) workflows, transactional workflows, and much more—all while providing up to 7.9x better price-performance than any other cloud data warehouses.

As with all AWS services, Amazon Redshift is a customer-obsessed service that recognizes there isn’t a one-size-fits-all for customers when it comes to data models, which is why Amazon Redshift supports multiple data models such as Star Schemas, Snowflake Schemas and Data Vault. This post discusses the most pressing needs when designing an enterprise-grade Data Vault and how those needs are addressed by Amazon Redshift in particular and AWS cloud in general. The first post in this two-part series discusses best practices for designing enterprise-grade data vaults of varying scale using Amazon Redshift.

Whether it’s a desire to easily retain data lineage directly within the data warehouse, establish a source-system agnostic data model within the data warehouse, or more easily comply with GDPR regulations, customers that implement a data vault model will benefit from this post’s discussion of considerations, best practices, and Amazon Redshift features as well as the AWS cloud capabilities relevant to the building of enterprise-grade data vaults. Building a starter version of anything can often be straightforward, but building something with enterprise-grade scale, security, resiliency, and performance typically requires knowledge and adherence to battle-tested best practices, and using the right tools and features in the right scenario.

Data Vault overview

For a brief review of the core Data Vault premise and concepts, refer to the first post in this series.

In the following sections, we discuss the most common areas of consideration that are critical for Data Vault implementations at scale: data protection, performance and elasticity, analytical functionality, cost and resource management, availability, and scalability. Although these areas can also be critical areas of consideration for any data warehouse data model, in our experience, these areas present their own flavor and special needs to achieve data vault implementations at scale.

Data protection

Security is always priority-one at AWS, and we see the same attention to security every day with our customers. Data security has many layers and facets, ranging from encryption at rest and in transit to fine-grained access controls and more. In this section, we explore the most common data security needs within the raw and business data vaults and the Amazon Redshift features that help achieve those needs.

Data encryption

Amazon Redshift encrypts data in transit by default. With the click of a button, you can configure Amazon Redshift to encrypt data at rest at any point in a data warehouse’s lifecycle, as shown in the following screenshot.

You can use either AWS Key Management Service (AWS KMS) or Hardware Security Module (HSM) to perform encryption of data at rest. If you use AWS KMS, you can either use an AWS managed key or customer managed key. For more information, refer to Amazon Redshift database encryption.

You can also modify cluster encryption after cluster creation, as shown in the following screenshot.

Moreover, Amazon Redshift Serverless is encrypted by default.

Fine-grained access controls

When it comes to achieving fine-grained access controls at scale, Data Vaults typically need to use both static and dynamic access controls. You can use static access controls to restrict access to databases, tables, rows, and columns to explicit users, groups, or roles. With dynamic access controls, you can mask part or all portions of a data item, such as a column based on a user’s role or some other functional analysis of a user’s privileges.

Amazon Redshift has long supported static access controls through the GRANT and REVOKE commands for databases, schemas, and tables, at row level and column level. Amazon Redshift also supports row-level security, where you can further restrict access to particular rows of the visible columns, as well as role-based access control, which helps simplify the management of security privileges in Amazon Redshift.

In the following example, we demonstrate how you can use GRANT and REVOKE statements to implement static access control in Amazon Redshift.

  1. First, create a table and populate it with credit card values:
    -- Create the credit cards table
    
    CREATE TABLE credit_cards 
    ( customer_id INT, 
    is_fraud BOOLEAN, 
    credit_card TEXT);
    
    --populate the table with sample values
    
    INSERT INTO credit_cards 
    VALUES
    (100,'n', '453299ABCDEF4842'),
    (100,'y', '471600ABCDEF5888'),
    (102,'n', '524311ABCDEF2649'),
    (102,'y', '601172ABCDEF4675'),
    (102,'n', '601137ABCDEF9710'),
    (103,'n', '373611ABCDEF6352');
    

  2. Create the user user1 and check permissions for user1 on the credit_cards table. We use SET SESSION AUTHORIZATION to switch to user1 in the current session:
       -- Create user
    
       CREATE USER user1 WITH PASSWORD '1234Test!';
    
       -- Check access permissions for user1 on credit_cards table
       SET SESSION AUTHORIZATION user1; 
       SELECT * FROM credit_cards; -- This will return permission defined error
    

  3. Grant SELECT access on the credit_cards table to user1:
    RESET SESSION AUTHORIZATION;
     
    GRANT SELECT ON credit_cards TO user1;
    

  4. Verify access permissions on the table credit_cards for user1:
    SET SESSION AUTHORIZATION user1;
    
    SELECT * FROM credit_cards; -- Query will return rows
    RESET SESSION AUTHORIZATION;

Data obfuscation

Static access controls are often useful to establish hard boundaries (guardrails) of the user communities that should be able to access certain datasets (for example, only those users that are part of the marketing user group should be allowed access to marketing data). However, what if access controls need to restrict only partial aspects of a field, not the entire field? Amazon Redshift supports partial, full, or custom data masking of a field through dynamic data masking. Dynamic data masking enables you to protect sensitive data in your data warehouse. You can manipulate how Amazon Redshift shows sensitive data to the user at query time without transforming it in the database by using masking policies.

In the following example, we achieve a full redaction of credit card numbers at runtime using a masking policy on the previously used credit_cards table.

  1. Create a masking policy that fully masks the credit card number:
    CREATE MASKING POLICY mask_credit_card_full 
    WITH (credit_card VARCHAR(256)) 
    USING ('000000XXXX0000'::TEXT);

  2. Attach mask_credit_card_full to the credit_cards table as the default policy. Note that all users will see this masking policy unless a higher priority masking policy is attached to them or their role.
    ATTACH MASKING POLICY mask_credit_card_full 
    ON credit_cards(credit_card) TO PUBLIC;

  3. Users will see credit card information being masked when running the following query
    SELECT * FROM credit_cards;

Centralized security policies

You can achieve a great deal of scale by combining static and dynamic access controls to span a broad swath of user communities, datasets, and access scenarios. However, what about datasets that are shared across multiple Redshift warehouses, as might be done between raw data vaults and business data vaults? How can scale be achieved with access controls for a dataset that resides on one Redshift warehouse but is authorized for use across multiple Redshift warehouses using Amazon Redshift data sharing?

The integration of Amazon Redshift with AWS Lake Formation enables centrally managed access and permissions for data sharing. Amazon Redshift data sharing policies are established in Lake Formation and will be honored by all of your Redshift warehouses.

Performance

It is not uncommon for sub-second SLAs to be associated with data vault queries, particularly when interacting with the business vault and the data marts sitting atop the business vault. Amazon Redshift delivers on that needed performance through a number of mechanisms such as caching, automated data model optimization, and automated query rewrites.

The following are common performance requirements for Data Vault implementations at scale:

  • Query and table optimization in support of high-performance query throughput
  • High concurrency
  • High-performance string-based data processing

Amazon Redshift features and capabilities for performance

In this section, we discuss Amazon Redshift features and capabilities that address those performance requirements.

Caching

Amazon Redshift uses multiple layers of caching to deliver subsecond response times for repeat queries. Through Amazon Redshift in-memory result set caching and compilation caching, workloads ranging from dashboarding to visualization to business intelligence (BI) that run repeat queries experience a significant performance boost.

With in-memory result set caching, queries that have a cached result set and no changes to the underlying data return immediately and typically within milliseconds.

The current generation RA3 node type is built on the AWS Nitro System with managed storage that uses high performance SSDs for your hot data and Amazon S3 for your cold data, providing ease of use, cost-effective storage, and fast query performance. In short, managed storage means fast retrieval for your most frequently accessed data and automated/managed identification of hot data by Amazon Redshift.

The large majority of queries in a typical production data warehouse are repeat queries, and data warehouses with data vault implementations observe the same pattern. The most optimal run profile for a repeat query is one that avoids costly query runtime interpretation, which is why queries in Amazon Redshift are compiled during the first run and the compiled code is cached in a global cache, providing repeat queries a significant performance boost.

Materialized views

Pre-computing the result set for repeat queries is a powerful mechanism for boosting performance. The fact that it automatically refreshes to reflect the latest changes in the underlying data is yet another powerful pattern for boosting performance. For example, consider the denormalization queries that might be run on the raw data vault to populate the business vault. It’s quite possible that some less-active source systems will have exhibited little to no changes in the raw data vault since the last run. Avoiding the hit of rerunning the business data vault population queries from scratch in those cases could be a tremendous boost to performance. Redshift materialized views provide that exact functionality by storing the precomputed result set of their backing query.

Queries that are similar to the materialized view’s backing query don’t have to rerun the same logic each time, because they can pull records from the existing result set. Developers and analysts can choose to create materialized views after analyzing their workloads to determine which queries would benefit. Materialized views also support automatic query rewriting to have Amazon Redshift rewrite queries to use materialized views, as well as auto refreshing materialized views, where Amazon Redshift can automatically refresh materialized views with up-to-date data from its base tables.

Alternatively, the automated materialized views (AutoMV) feature provides the same performance benefits of user-created materialized views without the maintenance overhead because Amazon Redshift automatically creates the materialized views based on observed query patterns. Amazon Redshift continually monitors the workload using machine learning and then creates new materialized views when they are beneficial. AutoMV balances the costs of creating and keeping materialized views up to date against expected benefits to query latency. The system also monitors previously created AutoMVs and drops them when they are no longer beneficial. AutoMV behavior and capabilities are the same as user-created materialized views. They are refreshed automatically and incrementally, using the same criteria and restrictions.

Also, whether the materialized views are user-created or auto-generated, Amazon Redshift automatically rewrites queries, without users to change queries, to use materialized views when there is enough of a similarity between the query and the materialized view’s backing query.

Concurrency scaling

Amazon Redshift automatically and elastically scales query processing power to provide consistently fast performance for hundreds of concurrent queries. Concurrency scaling resources are added to your Redshift warehouse transparently in seconds, as concurrency increases, to process read/write queries without wait time. When workload demand subsides, Amazon Redshift automatically shuts down concurrency scaling resources to save you cost. You can continue to use your existing applications and BI tools without any changes.

Because Data Vault allows for highly concurrent data processing and is primarily run within Amazon Redshift, concurrency scaling is the recommended way to handle concurrent transformation operations. You should avoid operations that aren’t supported by concurrency scaling.

Concurrent ingestion

One of the key attractions of Data Vault 2.0 is its ability to support high-volume concurrent ingestion from multiple source systems into the data warehouse. Amazon Redshift provides a number of options for concurrent ingestion, including batch and streaming.

For batch- and microbatch-based ingestion, we suggest using the COPY command in conjunction with CSV format. CSV is well supported by concurrency scaling. In case your data is already on Amazon S3 but in Bigdata formats like ORC or Parquet, always consider the trade-off of converting the data to CSV vs. non-concurrent ingestion. You can also use workload management to prioritize non-concurrent ingestion jobs to keep the throughput high.

For low-latency workloads, we suggest using the native Amazon Redshift streaming capability or the Amazon Redshift Zero ETL capability in conjunction with Amazon Aurora. By using Aurora as a staging layer for the raw data, you can handle small increments of data efficiently and with high concurrency, and then use this data inside your Redshift data warehouse without any extract, transform, and load (ETL) processes. For stream ingestion, we suggest using the native streaming feature (Amazon Redshift streaming ingestion) and have a dedicated stream for ingesting each table. This might require a stream processing solution upfront, which splits the input stream into the respective elements like the hub and the satellite record.

String-optimized compression

The Data Vault 2.0 methodology often involves time-sensitive lookup queries against potentially very large satellite tables (in terms of row count) that have low-cardinality hash/string indexes. Low-cardinality indexes and very large tables tend to work against time-sensitive queries. Amazon Redshift, however, provides a specialized compression method for low-cardinality string-based indexes called BYTEDICT. Using BYTEDICT creates a dictionary of the low-cardinality string indexes that allow Amazon Redshift to reads the rows even in a compressed state, thereby significantly improving performance. You can manually select the BYTEDICT compression method for a column, or alternatively rely on Amazon Redshift automated table optimization facilities to select it for you.

Support of transactional data lake frameworks

Data Vault 2.0 is an insert-only framework. Therefore, reorganizing data to save money is a challenge you may face. Amazon Redshift integrates seamlessly with S3 data lakes allowing you to perform data lake queries in your S3 using standard SQL as you would with native tables. This way, you can outsource less frequently used satellites to your S3 data lake, which is cheaper than keeping it as a native table.

Modern transactional lake formats like Apache Iceberg are also an excellent option to store this data. They ensure transactional safety and therefore ensure that your audit trail, which is a fundamental feature of Data Vault, doesn’t break.

We also see customers using these frameworks as a mechanism to implement incremental loads. Apache Iceberg lets you query for the last state for a given point in time. You can use this mechanism to optimize merge operations while still making the data accessible from within Amazon Redshift.

Amazon Redshift data sharing performance considerations

For large-scale Data Vault implementation, one of the preferred design principals is to have a separate Redshift data warehouse for each layer (staging, raw Data Vault, business Data Vault, and presentation data mart). These layers have separate Redshift provisioned or serverless warehouses according to their storage and compute requirements and use Amazon Redshift data sharing to share the data between these layers without physically moving the data.

Amazon Redshift data sharing enables you to seamlessly share live data across multiple Redshift warehouses without any data movement. Because the data sharing feature serves as the backbone in implementing large-scale Data Vaults, it’s important to understand the performance of Amazon Redshift in this scenario.

In a data sharing architecture, we have producer and consumer Redshift warehouses. The producer warehouse shares the data objects to one or more consumer warehouse for read purposes only without having to copy the data.

Producer/consumer Redshift cluster performance dependency

From a performance perspective, the producer (provisioned or serverless) warehouse is not responsible for query performance running on the consumer (provisioned or serverless) warehouse and has zero impact in terms of performance or activity on the producer Redshift warehouse. It depends on the consumer Redshift warehouse compute capacity. The producer warehouse is only responsible for the shared data.

Result set caching on the consumer Redshift cluster

Amazon Redshift uses result set caching to speed up the retrieval of data when it knows that the data in the underlying table has not changed. In a data sharing architecture, Amazon Redshift also uses result set caching on the consumer Redshift warehouse. This is quite helpful for repeatable queries that commonly occur in a data warehousing environment.

Best practices for materialized views in Data Vault with Amazon Redshift data sharing

In Data Vault implementation, the presentation data mart layer typically contains views or materialized views. There are two possible routes to create materialized views for the presentation data mart layer. First, create the materialized views on the producer Redshift warehouse (business data vault layer) and share materialized views with the consumer Redshift warehouse (dedicated data marts). Alternatively, share the table objects directly from the business data vault layer to the presentation data mart layer and build the materialized view on the shared objects directly on the consumer Redshift warehouse.

The second option is recommended in this case, because it gives us the flexibility of creating customized materialized views of data on each consumer according to the specific use case and simplifies the management because each data mart user can create and manage materialized views on their own Redshift warehouse rather than be dependent on the producer warehouse.

Table distribution implications in Amazon Redshift data sharing

Table distribution style and how data is distributed across Amazon Redshift plays a significant role in query performance. In Amazon Redshift data sharing, the data is distributed on the producer Redshift warehouse according to the distribution style defined for table. When we associate the data via a data share to the consumer Redshift warehouse, it maps to the same disk block layout. Also, a bigger consumer Redshift warehouse will result in better query performance for queries running on it.

Concurrency scaling

Concurrency scaling is also supported on both producer and consumer Redshift warehouses for read and write operations.

Cost and resource management

Given that multiple source systems and users will interact heavily with the data vault data warehouse, it’s a prudent best practice to enable usage and query limits to serve as guardrails against runaway queries and unapproved usage patterns. Furthermore, it often helps to have a systematic way for allocating service costs based on usage of the data vault to different source systems and user groups within your organization.

The following are common cost and resource management requirements for Data Vault implementations at scale:

  • Utilization limits and query resource guardrails
  • Advanced workload management
  • Chargeback capabilities

Amazon Redshift features and capabilities for cost and resource management

In this section, we discuss Amazon Redshift features and capabilities that address those cost and resource management requirements.

Utilization limits and query monitoring rules

Runaway queries and excessive auto scaling are likely to be the two most common runaway patterns observed with data vault implementations at scale.

A Redshift provisioned cluster supports usage limits for features such as Redshift Spectrum, concurrency scaling, and cross-Region data sharing. A concurrency scaling limit specifies the threshold of the total amount of time used by concurrency scaling in 1-minute increments. A limit can be specified for a daily, weekly, or monthly period (using UTC to determine the start and end of the period).

You can also define multiple usage limits for each feature. Each limit can have a different action, such as logging to system tables, alerting via Amazon CloudWatch alarms and optionally Amazon Simple Notification Service (Amazon SNS) subscriptions to that alarm (such as email or text), or disabling the feature outright until the next time period begins (such as the start of the month). When a usage limit threshold is reached, events are also logged to a system table.

Redshift provisioned clusters also support query monitoring rules to define metrics-based performance boundaries for workload management queues and the action that should be taken when a query goes beyond those boundaries. For example, for a queue dedicated to short-running queries, you might create a rule that cancels queries that run for more than 60 seconds. To track poorly designed queries, you might have another rule that logs queries that contain nested loops.

Each query monitoring rule includes up to three conditions, or predicates, and one query action (such as stop, hop, or log). A predicate consists of a metric, a comparison condition (=, <, or >), and a value. If all of the predicates for any rule are met, that rule’s action is triggered. Amazon Redshift evaluates metrics every 10 seconds and if more than one rule is triggered during the same period, Amazon Redshift initiates the most severe action (stop, then hop, then log).

Redshift Serverless also supports usage limits where you can specify the base capacity according to your price-performance requirements. You can also set the maximum RPU (Redshift Processing Units) hours used per day, per week, or per month to keep the cost predictable and specify different actions, such as write to system table, receive an alert, or turn off user queries when the limit is reached. A cross-Region data sharing usage limit is also supported, which limits how much data transferred from the producer Region to the consumer Region that consumers can query.

You can also specify query limits in Redshift Serverless to stop poorly performing queries that exceed the threshold value.

Auto workload management

Not all queries have the same performance profile or priority, and data vault queries are no different. Amazon Redshift workload management (WLM) adapts in real time to the priority, resource allocation, and concurrency settings required to optimally run different data vault queries. These queries could consist of a high number of joins between the hubs, links, and satellites tables; large-scale scans of the satellite tables; or massive aggregations. Amazon Redshift WLM enables you to flexibly manage priorities within workloads so that, for example, short or fast-running queries won’t get stuck in queues behind long-running queries.

You can use automatic WLM to maximize system throughput and use resources effectively. You can enable Amazon Redshift to manage how resources are divided to run concurrent queries with automatic WLM. Automatic WLM manages the resources required to run queries. Amazon Redshift determines how many queries run concurrently and how much memory is allocated to each dispatched query.

Chargeback metadata

Amazon Redshift provides different pricing models to cater to different customer needs. On-demand pricing offers the greatest flexibility, whereas Reserved Instances provide significant discounts for predictable and steady usage scenarios. Redshift Serverless provides a pay-as-you-go model that is ideal for sporadic workloads.

However, with any of these pricing models, Amazon Redshift customers can attribute cost to different users. To start, Amazon Redshift provides itemized billing like many other AWS services in AWS Cost Explorer to attain the overall cost of using Amazon Redshift. Moreover, the cross-group collaboration (data sharing) capability of Amazon Redshift enables a more explicit and structured chargeback model to different teams.

Availability

In the modern data organization, data warehouses are no longer used purely to perform historical analysis in batches overnight with relatively forgiving SLAs, Recovery Time Objectives (RTOs), and Recovery Point Objectives (RPOs). They have become mission-critical systems in their own right that are used for both historical analysis and near-real-time data analysis. Data Vault systems at scale very much fit that mission-critical profile, which makes availability key.

The following are common availability requirements for Data Vault implementations at scale:

  • RTO of near-zero
  • RPO of near-zero
  • Automated failover
  • Advanced backup management
  • Commercial-grade SLA

Amazon Redshift features and capabilities for availability

In this section, we discuss the features and capabilities in Amazon Redshift that address those availability requirements.

Separation of storage and compute

AWS and Amazon Redshift are inherently resilient. With Amazon Redshift, there’s no additional cost for active-passive disaster recovery. Amazon Redshift replicates all of your data within your data warehouse when it is loaded and also continuously backs up your data to Amazon S3. Amazon Redshift always attempts to maintain at least three copies of your data (the original and replica on the compute nodes, and a backup in Amazon S3).

With separation of storage and compute and Amazon S3 as the persistence layer, you can achieve an RPO of near-zero, if not zero itself.

Cluster relocation to another Availability Zone

Amazon Redshift provisioned RA3 clusters support cluster relocation to another Availability Zone in events where cluster operation in the current Availability Zone is not optimal, without any data loss or changes to your application. Cluster relocation is available free of charge; however, relocation might not always be possible if there is a resource constraint in the target Availability Zone.

Multi-AZ deployment

For many customers, the cluster relocation feature is sufficient; however, enterprise data warehouse customers require a low RTO and higher availability to support their business continuity with minimal impact to applications.

Amazon Redshift supports Multi-AZ deployment for provisioned RA3 clusters.

A Redshift Multi-AZ deployment uses compute resources in multiple Availability Zones to scale data warehouse workload processing as well as provide an active-active failover posture. In situations where there is a high level of concurrency, Amazon Redshift will automatically use the resources in both Availability Zones to scale the workload for both read and write requests using active-active processing. In cases where there is a disruption to an entire Availability Zone, Amazon Redshift will continue to process user requests using the compute resources in the sister Availability Zone.

With features such as multi-AZ deployment, you can achieve a low RTO, should there ever be a disruption to the primary Redshift cluster or an entire Availability Zone.

Automated backup

Amazon Redshift automatically takes incremental snapshots that track changes to the data warehouse since the previous automated snapshot. Automated snapshots retain all of the data required to restore a data warehouse from a snapshot. You can create a snapshot schedule to control when automated snapshots are taken, or you can take a manual snapshot any time.

Automated snapshots can be taken as often as once every hour and retained for up to 35 days at no additional charge to the customer. Manual snapshots can be kept indefinitely at standard Amazon S3 rates. Furthermore, automated snapshots can be automatically replicated to another Region and stored there as a disaster recovery site also at no additional charge (with the exception of data transfer charges across Regions) and manual snapshots can also be replicated with standard Amazon S3 rates applying (and data transfer costs).

Amazon Redshift SLA

As a managed service, Amazon Redshift frees you from being the first and only line of defense against disruptions. AWS will use commercially reasonable efforts to make Amazon Redshift available with a monthly uptime percentage for each Multi-AZ Redshift cluster during any monthly billing cycle, of at least 99.99% and for multi-node cluster, at least 99.9%. In the event that Amazon Redshift doesn’t meet the Service Commitment, you will be eligible to receive a Service Credit.

Scalability

One of the major motivations of organizations migrating to the cloud is improved and increased scalability. With Amazon Redshift, Data Vault systems will always have a number of scaling options available to them.

The following are common scalability requirements for Data Vault implementations at scale:

  • Automated and fast-initiating horizontal scaling
  • Robust and performant vertical scaling
  • Data reuse and sharing mechanisms

Amazon Redshift features and capabilities for scalability

In this section, we discuss the features and capabilities in Amazon Redshift that address those scalability requirements.

Horizontal and vertical scaling

Amazon Redshift uses concurrency scaling automatically to support virtually unlimited horizontal scaling of concurrent users and concurrent queries, with consistently fast query performance. Furthermore, concurrency scaling requires no downtime, supports read/write operations, and is typically the most impactful and used scaling option for customers during normal business operations to maintain consistent performance.

With Amazon Redshift provisioned warehouse, as your data warehousing capacity and performance needs to change or grow, you can vertically scale your cluster to make the best use of the computing and storage options that Amazon Redshift provides. Resizing your cluster by changing the node type or number of nodes can typically be achieved in 10–15 minutes. Vertical scaling typically occurs much less frequently in response to persistent and organic growth and is typically performed during a planned maintenance window when the short downtime doesn’t impact business operations.

Explicit horizontal or vertical resize and pause operations can be automated per a schedule (for example, development clusters can be automatically scaled down or paused for the weekends). Note that the storage of paused clusters remains accessible to clusters with which their data was shared.

For resource-intensive workloads that might benefit from a vertical scaling operation vs. concurrency scaling, there are also other best-practice options that avoid downtime, such as deploying the workload onto its own Redshift Serverless warehouse while using data sharing.

Redshift Serverless measures data warehouse capacity in RPUs, which are resources used to handle workloads. You can specify the base data warehouse capacity Amazon Redshift uses to serve queries (ranging from as little as 8 RPUs to as high as 512 RPUs) and change the base capacity at any time.

Data sharing

Amazon Redshift data sharing is a secure and straightforward way to share live data for read purposes across Redshift warehouses within the same or different accounts and Regions. This enables high-performance data access while preserving workload isolation. You can have separate Redshift warehouses, either provisioned or serverless, for different use cases according to your compute requirement and seamlessly share data between them.

Common use cases for data sharing include setting up a central ETL warehouse to share data with many BI warehouses to provide read workload isolation and chargeback, offering data as a service and sharing data with external consumers, multiple business groups within an organization, sharing and collaborating on data to gain differentiated insights, and sharing data between development, test, and production environments.

Reference architecture

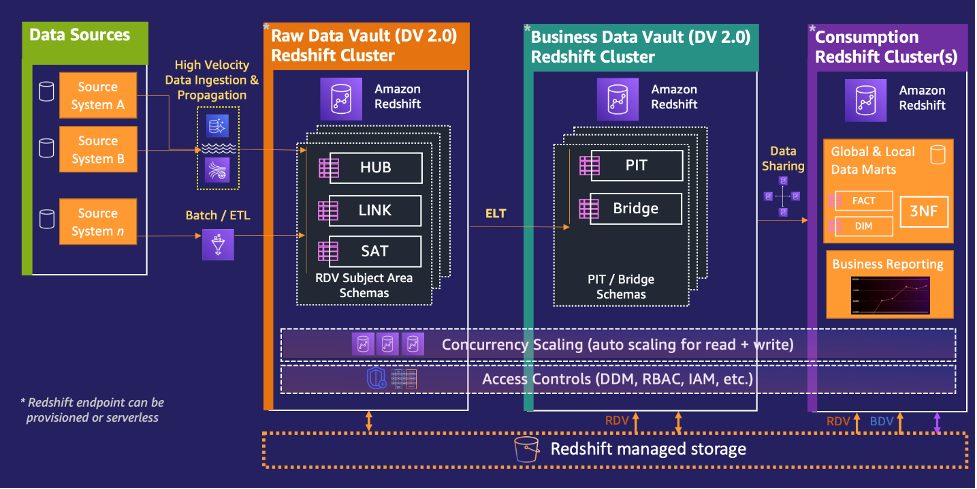
The diagram in this section shows one possible reference architecture of a Data Vault 2.0 system implemented with Amazon Redshift.

We suggest using three different Redshift warehouses to run a Data Vault 2.0 model in Amazon Redshift. The data between these data warehouses is shared via Amazon Redshifts data sharing and allows you to consume data from a consumer data warehouse even if the provider data warehouse is inactive.

  • Raw Data Vault – The RDV data warehouse hosts hubs, links, and satellite tables. For large models, you can additionally slice the RDV into additional data warehouses to even better adopt the data warehouse sizing to your workload patterns. Data is ingested via the patterns described in the previous section as batch or high velocity data.
  • Business Data Vault – The BDV data warehouse hosts bridge and point in time (PIT) tables. These tables are computed based on the RDV tables using Amazon Redshift. Materialized or automatic materialized views are straightforward mechanisms to create those.
  • Consumption cluster – This data warehouse contains query-optimized data formats and marts. Users interact with this layer.

If the workload pattern is unknown, we suggest starting with a Redshift Serverless warehouse and learning the workload pattern. You can easily migrate between a serverless and provisioned Redshift cluster at a later stage based on your processing requirements, as discussed in Part 1 of this series.

Best practices building a Data Vault warehouse on AWS

In this section, we cover how the AWS Cloud as a whole plays its role in building an enterprise-grade Data Vault warehouse on Amazon Redshift.

Education

Education is a fundamental success factor. Data Vault is more complex than traditional data modeling methodologies. Before you start the project, make sure everyone understands the principles of Data Vault. Amazon Redshift is designed to be very easy to use, but to ensure the most optimal Data Vault implementation on Amazon Redshift, gaining a good understanding of how Amazon Redshift works is recommended. Start with free resources like reaching out to your AWS account representative to schedule a free Amazon Redshift Immersion Day or train for the AWS Analytics specialty certification.

Automation

Automation is a major benefit of Data Vault. This will increase efficiency and consistency across your data landscape. Most customers focus on the following aspects when automating Data Vault:

  • Automated DDL and DML creation, including modeling tools especially for the raw data vault
  • Automated ingestion pipeline creation
  • Automated metadata and lineage support

Depending on your needs and skills, we typically see three different approaches:

  • DSL – This is a common tool for generating data vault models and flows with Domain Specific Languages (DSL). Popular frameworks for building such DSLs are EMF with Xtext or MPS. This solution provides the most flexibility. You directly build your business vocabulary into the application and generate documentation and business glossary along with the code. This approach requires the most skill and biggest resource investment.
  • Modeling tool – You can build on an existing modeling language like UML 2.0. Many modeling tools come with code generators. Therefore, you don’t need to build your own tool, but these tools are often hard to integrate into modern DevOps pipelines. They also require UML 2.0 knowledge, which raises the bar for non-tech users.
  • Buy – There are a number of different third-party solutions that integrate well into Amazon Redshift and are available via AWS Marketplace.

Whichever approach of the above-mentioned approaches you choose, all three approaches offer multiple benefits. For example, you can take away repetitive tasks from your development team and enforce modeling standards like data types, data quality rules, and naming conventions. To generate the code and deploy it, you can use AWS DevOps services. As part of this process, you save the generated metadata to the AWS Glue Data Catalog, which serves as a central technical metadata catalog. You then deploy the generated code to Amazon Redshift (SQL scripts) and to AWS Glue.

We designed AWS CloudFormation for automation; it’s the AWS-native way of automating infrastructure creation and management. A major use case for infrastructure as code (IaC) is to create new ingestion pipelines for new data sources or add new entities to existing one.

You can also use our new AI coding tool Amazon CodeWhisperer, which helps you quickly write secure code by generating whole line and full function code suggestions in your IDE in real time, based on your natural language comments and surrounding code. For example, CodeWhisperer can automatically take a prompt such as “get new files uploaded in the last 24 hours from the S3 bucket” and suggest appropriate code and unit tests. This can greatly reduce development effort in writing code, for example for ETL pipelines or generating SQL queries, and allow more time for implementing new ideas and writing differentiated code.

Operations

As previously mentioned, one of the benefits of Data Vault is the high level of automation which, in conjunction with serverless technologies, can lower the operating efforts. On the other hand, some industry products come with built-in schedulers or orchestration tools, which might increase operational complexity. By using AWS-native services, you’ll benefit from integrated monitoring options of all AWS services.

Conclusion

In this series, we discussed a number of crucial areas required for implementing a Data Vault 2.0 system at scale, and the Amazon Redshift capabilities and AWS ecosystem that you can use to satisfy those requirements. There are many more Amazon Redshift capabilities and features that will surely come in handy, and we strongly encourage current and prospective customers to reach out to us or other AWS colleagues to delve deeper into Data Vault with Amazon Redshift.


About the Authors

Asser Moustafa is a Principal Analytics Specialist Solutions Architect at AWS based out of Dallas, Texas. He advises customers globally on their Amazon Redshift and data lake architectures, migrations, and visions—at all stages of the data ecosystem lifecycle—starting from the POC stage to actual production deployment and post-production growth.

Philipp Klose is a Global Solutions Architect at AWS based in Munich. He works with enterprise FSI customers and helps them solve business problems by architecting serverless platforms. In this free time, Philipp spends time with his family and enjoys every geek hobby possible.

Saman Irfan is a Specialist Solutions Architect at Amazon Web Services. She focuses on helping customers across various industries build scalable and high-performant analytics solutions. Outside of work, she enjoys spending time with her family, watching TV series, and learning new technologies.
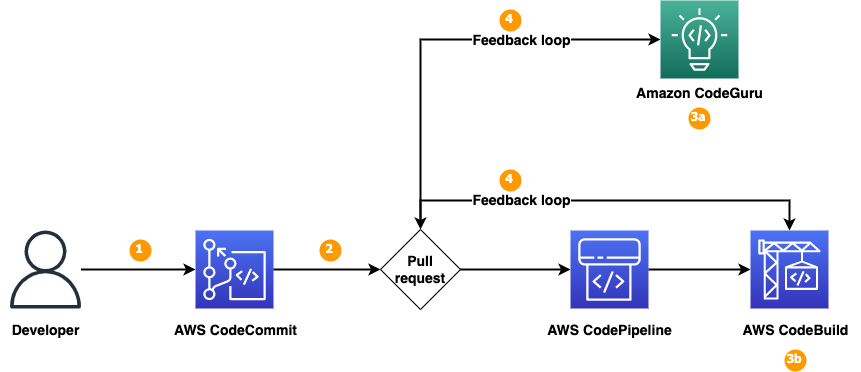
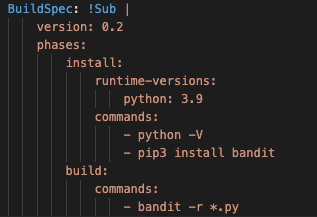
Use scalable controls for AWS services accessing your resources

Post Syndicated from James Greenwood original https://aws.amazon.com/blogs/security/use-scalable-controls-for-aws-services-accessing-your-resources/

Sometimes you want to configure an AWS service to access your resource in another service. For example, you can configure AWS CloudTrail, a service that monitors account activity across your AWS infrastructure, to write log data to your bucket in Amazon Simple Storage Service (Amazon S3). When you do this, you want assurance that the service will only access your resource on your behalf—you don’t want an untrusted entity to be able to use the service to access your resource. Before today, you could achieve this by using the two AWS Identity and Access Management (IAM) condition keys, aws:SourceAccount and aws:SourceArn. You can use these condition keys to help make sure that a service accesses your resource only on behalf of specific accounts or resources that you trust. However, because these condition keys require you to specify individual accounts and resources, they can be difficult to manage at scale, especially in larger organizations.

Recently, IAM launched two new condition keys that can help you achieve this in a more scalable way that is simpler to manage within your organization:

  • aws:SourceOrgID — use this condition key to make sure that an AWS service can access your resources only when the request originates from a particular organization ID in AWS Organizations.
  • aws:SourceOrgPaths — use this condition key to make sure that an AWS service can access your resources only when the request originates from one or more organizational units (OUs) in your organization.

In this blog post, we describe how you can use the four available condition keys, including the two new ones, to help you control how AWS services access your resources.

Background

Imagine a scenario where you configure an AWS service to access your resource in another service. Let’s say you’re using Amazon CloudWatch to observe resources in your AWS environment, and you create an alarm that activates when certain conditions occur. When the alarm activates, you want it to publish messages to a topic that you create in Amazon Simple Notification Service (Amazon SNS) to generate notifications.

Figure 1 depicts this process.

Figure 1: Amazon CloudWatch publishing messages to an SNS topic

Figure 1: Amazon CloudWatch publishing messages to an SNS topic

In this scenario, there’s a resource-based policy controlling access to your SNS topic. For CloudWatch to publish messages to it, you must configure the policy to allow access by CloudWatch. When you do this, you identify CloudWatch using an AWS service principal, in this case cloudwatch.amazonaws.com.

Cross-service access

This is an example of a common pattern known as cross-service access. With cross-service access, a calling service accesses your resource in a called service, and a resource-based policy attached to your resource grants access to the calling service. The calling service is identified using an AWS service principal in the form <SERVICE-NAME>.amazonaws.com, and it accesses your resource on behalf of an originating resource, such as a CloudWatch alarm.

Figure 2 shows cross-service access.

Figure 2: Cross-service access

Figure 2: Cross-service access

When you configure cross-service access, you want to make sure that the calling service will access your resource only on your behalf. That means you want the originating resource to be controlled by someone whom you trust. If an untrusted entity creates their own CloudWatch alarm in their AWS environment, for example, then their alarm should not be able to publish messages to your SNS topic.

If an untrusted entity could use a calling service to access your resource on their behalf, it would be an example of what’s known as the confused deputy problem. The confused deputy problem is a security issue in which an entity that doesn’t have permission to perform an action coerces a more privileged entity (in this case, a calling service) to perform the action instead.

Use condition keys to help prevent cross-service confused deputy issues

AWS provides global condition keys to help you prevent cross-service confused deputy issues. You can use these condition keys to control how AWS services access your resources.

Before today, you could use the aws:SourceAccount or aws:SourceArn condition keys to make sure that a calling service accesses your resource only when the request originates from a specific account (with aws:SourceAccount) or a specific originating resource (with aws:SourceArn). However, there are situations where you might want to allow multiple resources or accounts to use a calling service to access your resource. For example, you might want to create many VPC flow logs in an organization that publish to a central S3 bucket. To achieve this using the aws:SourceAccount or aws:SourceArn condition keys, you must enumerate all the originating accounts or resources individually in your resource-based policies. This can be difficult to manage, especially in large organizations, and can potentially cause your resource-based policy documents to reach size limits.

Now, you can use the new aws:SourceOrgID or aws:SourceOrgPaths condition keys to make sure that a calling service accesses your resource only when the request originates from a specific organization (with aws:SourceOrgID) or a specific organizational unit (with aws:SourceOrgPaths). This helps avoid the need to update policies when accounts are added or removed, reduces the size of policy documents, and makes it simpler to create and review policy statements.

The following table summarizes the four condition keys that you can use to help prevent cross-service confused deputy issues. These keys work in a similar way, but with different levels of granularity.

Use case Condition key Value Allowed operators Single/multi valued Example value
Allow a calling service to access your resource only on behalf of an organization that you trust. aws:SourceOrgID AWS organization ID of the resource making a cross-service access request String operators Single-valued key o-a1b2c3d4e5
Allow a calling service to access your resource only on behalf of an organizational unit (OU) that you trust. aws:SourceOrgPaths Organization entity paths of the resource making a cross-service access request Set operators and string operators Multivalued key o-a1b2c3d4e5/r-ab12/ou-ab12-11111111/ou-ab12-22222222/
Allow a calling service to access your resource only on behalf of an account that you trust. aws:SourceAccount AWS account ID of the resource making a cross-service access request String operators Single-valued key 111122223333
Allow a calling service to access your resource only on behalf of a resource that you trust. aws:SourceArn Amazon Resource Name (ARN) of the resource making a cross- service access request ARN operators (recommended) or string operators Single-valued key arn:aws:cloudwatch:eu-west-1:111122223333:alarm:myalarm

When to use the condition keys

AWS recommends that you use these condition keys in any resource-based policy statements that allow access by an AWS service, except where the relevant condition key is not yet supported by the service. To find out whether a condition key is supported by a particular service, see AWS global condition context keys in the AWS Identity and Access Management User Guide.

Note: Only use these condition keys in resource-based policies that allow access by an AWS service. Don’t use them in other use cases, including identity-based policies and service control policies (SCPs), where these condition keys won’t be populated.

Use condition keys for defense in depth

AWS services use a variety of mechanisms to help prevent cross-service confused deputy issues, and the details vary by service. For example, where a calling service accesses an S3 bucket, some services use S3 prefixes to help prevent confused deputy issues. For more information, see the relevant service documentation.

Where supported by the service, AWS recommends that you use the condition keys we describe in this post regardless of whether the service has another mechanism in place to help prevent cross-service confused deputy issues. This helps to make your intentions explicit, provide defense in depth, and guard against misconfigurations.

Example use cases

Let’s walk through some example use cases to learn how to use these condition keys in practice.

First, imagine you’re using Amazon Virtual Private Cloud (Amazon VPC) to manage logically isolated virtual networks. In Amazon VPC, you can configure flow logs, which capture information about your network traffic. Let’s say you want a flow log to write data into an S3 bucket for later analysis. This process is depicted in Figure 3.

Figure 3: Amazon VPC writing flow logs to an S3 bucket

Figure 3: Amazon VPC writing flow logs to an S3 bucket

This constitutes another cross-service access scenario. In this case, Amazon VPC is the calling service, Amazon S3 is the called service, the VPC flow log is the originating resource, and the S3 bucket is your resource in the called service.

To allow access, the resource-based policy for your S3 bucket (known as a bucket policy) must allow Amazon VPC to put objects there. The Principal element in this policy specifies the AWS service principal of the service that will access the resource, which for VPC flow logs is delivery.logs.amazonaws.com.

Initial policy without confused deputy prevention

The following is an initial version of the bucket policy that allows Amazon VPC to put objects in the bucket but doesn’t yet provide confused deputy prevention. We’re showing this policy for illustration purposes; don’t use it in its current form.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "PARTIAL-EXAMPLE-DO-NOT-USE",
            "Effect": "Allow",
            "Principal": {
                "Service": "delivery.logs.amazonaws.com"
            },
            "Action": "s3:PutObject",
            "Resource": "arn:aws:s3:::<DOC-EXAMPLE-BUCKET>/*"
        }
    ]
}

Note: For simplicity, we only show one of the policy statements that you need to allow VPC flow logs to write to a bucket. In a real-life bucket policy for flow logs, you need two policy statements: one allowing actions on the bucket, and one allowing actions on the bucket contents. These are described in Publish flow logs to Amazon S3. Both policy statements work in the same way with respect to confused deputy prevention.

This policy statement allows Amazon VPC to put objects in the bucket. However, it allows Amazon VPC to do that on behalf of any flow log in any account. There’s nothing in the policy to tell Amazon VPC that it should access this bucket only if the flow log belongs to a specific organization, OU, account, or resource that you trust.

Let’s now update the policy to help prevent cross-service confused deputy issues. For the rest of this post, the remaining policy samples provide confused deputy protection, but at different levels of granularity.

Specify a trusted organization

Continuing with the previous example, imagine that you now have an organization in AWS Organizations, and you want to create VPC flow logs in various accounts within your organization that publish to a central S3 bucket. You want Amazon VPC to put objects in the bucket only if the request originates from a flow log that resides in your organization.

You can achieve this by using the new aws:SourceOrgID condition key. In a cross-service access scenario, this condition key evaluates to the ID of the organization that the request came from. You can use this condition key in the Condition element of a resource-based policy to allow actions only if aws:SourceOrgID matches the ID of a specific organization, as shown in the following example. In your own policy, make sure to replace <DOC-EXAMPLE-BUCKET> and <MY-ORGANIZATION-ID> with your own information.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "VPCLogsDeliveryWrite",
            "Effect": "Allow",
            "Principal": {
                "Service": "delivery.logs.amazonaws.com"
            },
            "Action": "s3:PutObject",
            "Resource": "arn:aws:s3:::<DOC-EXAMPLE-BUCKET>/*",
            "Condition": {
                "StringEquals": {
                    "aws:SourceOrgID": "<MY-ORGANIZATION-ID>"
                }
            }
        }
    ]
}

The revised policy states that Amazon VPC can put objects in the bucket only if the request originates from a flow log in your organization. Now, if someone creates a flow log outside your organization and configures it to access your bucket, they will get an access denied error.

You can use aws:SourceOrgID in this way to allow a calling service to access your resource only if the request originates from a specific organization, as shown in Figure 4.

Figure 4: Specify a trusted organization using aws:SourceOrgID

Figure 4: Specify a trusted organization using aws:SourceOrgID

Specify a trusted OU

What if you don’t want to trust your entire organization, but only part of it? Let’s consider a different scenario. Imagine that you want to send messages from Amazon SNS into a queue in Amazon Simple Queue Service (Amazon SQS) so they can be processed by consumers. This is depicted in Figure 5.

Figure 5: Amazon SNS sending messages to an SQS queue

Figure 5: Amazon SNS sending messages to an SQS queue

Now imagine that you want your SQS queue to receive messages only if they originate from an SNS topic that resides in a specific organizational unit (OU) in your organization. For example, you might want to allow messages only if they originate from a production OU that is subject to change control.

You can achieve this by using the new aws:SourceOrgPaths condition key. As before, you use this condition key in a resource-based policy attached to your resource. In a cross-service access scenario, this condition key evaluates to the AWS Organizations entity path that the request came from. An entity path is a text representation of an entity within an organization.

You build an entity path for an OU by using the IDs of the organization, root, and all OUs in the path down to and including the OU. For example, consider the organizational structure shown in Figure 6.

Figure 6: Example organization structure

Figure 6: Example organization structure

In this example, you can specify the Prod OU by using the following entity path:

o-a1b2c3d4e5/r-ab12/ou-ab12-11111111/ou-ab12-22222222/

For more information about how to construct an entity path, see Understand the AWS Organizations entity path.

Let’s now match the aws:SourceOrgPaths condition key against a specific entity path in the Condition element of a resource-based policy for an SQS queue. In your own policy, make sure to replace <MY-QUEUE-ARN> and <MY-ENTITY-PATH> with your own information.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "Allow-SNS-SendMessage",
            "Effect": "Allow",
            "Principal": {
                "Service": "sns.amazonaws.com"
            },
            "Action": "sqs:SendMessage",
            "Resource": "<MY-QUEUE-ARN>",
            "Condition": {
                "Null": {
                    "aws:SourceOrgPaths": "false"
                },
                "ForAllValues:StringEquals": {
                    "aws:SourceOrgPaths": "<MY-ENTITY-PATH>"
                }
            }
        }
    ]
}

Note: aws:SourceOrgPaths is a multivalued condition key, which means it’s capable of having multiple values in the request context. At the time of writing, it contains a single entity path if the request originates from an account in an organization, and a null value if the request originates from an account that’s not in an organization. Because this key is multivalued, you need to use both a set operator and a string operator to compare values.

In this policy, there are two conditions in the Condition block. The first uses the Null condition operator and compares with a false value to confirm that the condition key’s value is not null. The second uses set operator ForAllValues, which returns true if every condition key value in the request matches at least one value in your policy condition, and string operator StringEquals, which requires an exact match with a value specified in your policy condition.

Note: The reason for the null check is that set operator ForAllValues returns true when a condition key resolves to null. With an Allow effect and the null check in place, access is denied if the request originates from an account that’s not in an organization.

With this policy applied to your SQS queue, Amazon SNS can send messages to your queue only if the message came from an SNS topic in a specific OU.

You can use aws:SourceOrgPaths in this way to allow a calling service to access your resource only if the request originates from a specific organizational unit, as shown in Figure 7.

Figure 7: Specify a trusted OU using aws:SourceOrgPaths

Figure 7: Specify a trusted OU using aws:SourceOrgPaths

Specify a trusted OU and its children

In the previous example, we specified a trusted OU, but that didn’t include its child OUs. What if you want to include its children as well?

You can achieve this by replacing the string operator StringEquals with StringLike. This allows you to use wildcards in the entity path. Using the organization structure from the previous example, the following Condition evaluates to true only if the condition key value is not null and the request originates from the Prod OU or any of its child OUs.

"Condition": {
    "Null": {
        "aws:SourceOrgPaths": "false"
    },
    "ForAllValues:StringLike": {
        "aws:SourceOrgPaths": "o-a1b2c3d4e5/r-ab12/ou-ab12-11111111/ou-ab12-22222222/*"
    }
}

Specify a trusted account

If you want to be more granular, you can allow a service to access your resource only if the request originates from a specific account. You can achieve this by using the aws:SourceAccount condition key. In a cross-service access scenario, this condition key evaluates to the ID of the account that the request came from. 

The following Condition evaluates to true only if the request originates from the account that you specify in the policy. In your own policy, make sure to replace <MY-ACCOUNT-ID> with your own information.

"Condition": {
    "StringEquals": {
        "aws:SourceAccount": "<MY-ACCOUNT-ID>"
    }
}

You can use this condition element within a resource-based policy to allow a calling service to access your resource only if the request originates from a specific account, as shown in Figure 8.

Figure 8: Specify a trusted account using aws:SourceAccount

Figure 8: Specify a trusted account using aws:SourceAccount

Specify a trusted resource

If you want to be even more granular, you can allow a service to access your resource only if the request originates from a specific resource. For example, you can allow Amazon SNS to send messages to your SQS queue only if the request originates from a specific topic within Amazon SNS.

You can achieve this by using the aws:SourceArn condition key. In a cross-service access scenario, this condition key evaluates to the Amazon Resource Name (ARN) of the originating resource. This provides the most granular form of cross-service confused deputy prevention.

The following Condition evaluates to true only if the request originates from the resource that you specify in the policy. In your own policy, make sure to replace <MY-RESOURCE-ARN> with your own information.

"Condition": {
    "ArnEquals": {
        "aws:SourceArn": "<MY-RESOURCE-ARN>"
    }
}

Note: AWS recommends that you use an ARN operator rather than a string operator when comparing ARNs. This example uses ArnEquals to match the condition key value against the ARN specified in the policy.

You can use this condition element within a resource-based policy to allow a calling service to access your resource only if the request comes from a specific originating resource, as shown in Figure 9.

Figure 9: Specify a trusted resource using aws:SourceArn

Figure 9: Specify a trusted resource using aws:SourceArn

Specify multiple trusted resources, accounts, OUs, or organizations

The four condition keys allow you to specify multiple trusted entities by matching against an array of values. This allows you to specify multiple trusted resources, accounts, OUs, or organizations in your policies.

Conclusion

In this post, you learned about cross-service access, in which an AWS service communicates with another AWS service to access your resource. You saw that it’s important to make sure that such services access your resources only on your behalf in order to help avoid cross-service confused deputy issues.

We showed you how to help prevent cross-service confused deputy issues by using two new condition keys aws:SourceOrgID and aws:SourceOrgPaths, as well as the other available condition keys aws:SourceAccount and aws:SourceArn. You learned that you should use these condition keys in any resource-based policy statements that allow access by an AWS service, if the condition key is supported by the service. This helps make sure that a calling service can access your resource only when the request originates from a specific organization, OU, account, or resource that you trust.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on AWS IAM re:Post or contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Author

James Greenwood

James is a Principal Security Solutions Architect who helps AWS Financial Services customers meet their security and compliance objectives in the AWS Cloud. James has a background in identity and access management, authentication, credential management, and data protection with more than 20 years of experience in the financial services industry.

Sophia Yang

Sophia Yang

Sophia is a Senior Product Manager on the AWS Identity and Access Management (IAM) service. She is passionate about enabling customers to build and innovate in AWS in a secure manner.

Introducing instance maintenance policy for Amazon EC2 Auto Scaling

Post Syndicated from Macey Neff original https://aws.amazon.com/blogs/compute/introducing-instance-maintenance-policy-for-amazon-ec2-auto-scaling/

This post is written by Ahmed Nada, Principal Solutions Architect, Flexible Compute and Kevin OConnor, Principal Product Manager, Amazon EC2 Auto Scaling.

Amazon Web Services (AWS) customers around the world trust Amazon EC2 Auto Scaling to provision, scale, and manage Amazon Elastic Compute Cloud (Amazon EC2) capacity for their workloads. Customers have come to rely on Amazon EC2 Auto Scaling instance refresh capabilities to drive deployments of new EC2 Amazon Machine Images (AMIs), change EC2 instance types, and make sure their code is up-to-date.

Currently, EC2 Auto Scaling uses a combination of ‘launch before terminate’ and ‘terminate and launch’ behaviors depending on the replacement cause. Customers have asked for more control over when new instances are launched, so they can minimize any potential disruptions created by replacing instances that are actively in use. This is why we’re excited to introduce instance maintenance policy for Amazon EC2 Auto Scaling, an enhancement that provides customers with greater control over the EC2 instance replacement processes to make sure instances are replaced in a way that aligns with performance priorities and operational efficiencies while minimizing Amazon EC2 costs.

This post dives into varying ways to configure an instance maintenance policy and gives you tools to use it in your Amazon EC2 Auto Scaling groups.

Background

AWS launched Amazon EC2 Auto Scaling in 2009 with the goal of simplifying the process of managing Amazon EC2 capacity. Since then, we’ve continued to innovate with advanced features like predictive scaling, attribute-based instance selection, and warm pools.

A fundamental Amazon EC2 Auto Scaling capability is replacing instances based on instance health, due to Amazon EC2 Spot Instance interruptions, or in response to an instance refresh operation. The instance refresh capability allows you to maintain a fleet of healthy and high-performing EC2 instances in your Amazon EC2 Auto Scaling group. In some situations, it’s possible that terminating instances before launching a replacement can impact performance, or in the worst case, cause downtime for your applications. No matter what your requirements are, instance maintenance policy allows you to fine-tune the instance replacement process to match your specific needs.

Overview

Instance maintenance policy adds two new Amazon EC2 Auto Scaling group settings: minimum healthy percentage (MinHealthyPercentage) and maximum healthy percentage (MaxHealthyPercentage). These values represent the percentage of the group’s desired capacity that must be in a healthy and running state during instance replacement. Values for MinHealthyPercentage can range from 0 to 100 percent and from 100 to 200 percent for MaxHealthyPercentage. These settings are applied to all events that lead to instance replacement, such as Health-check based replacement, Max Instance Lifetime, EC2 Spot Capacity Rebalancing, Availability Zone rebalancing, Instance Purchase Option Rebalancing, and Instance refresh. You can also override the group-level instance maintenance policy during instance refresh operations to meet specific deployment use cases.

Before launching instance maintenance policy, an Amazon EC2 Auto Scaling group would use the previously described behaviors when replacing instances. By setting the MinHealthyPercentage of the instance maintenance policy to 100% and the MaxHealthyPercentage to a value greater than 100%, the Amazon EC2 Auto Scaling group first launches replacement instances and waits for them to become available before terminating the instances being replaced.

Setting up instance maintenance policy

You can add an instance maintenance policy to new or existing Amazon EC2 Auto Scaling groups using the AWS Management Console, AWS Command Line Interface (AWS CLI), AWS SDK, AWS CloudFormation, and Terraform.

When creating or editing Amazon EC2 Auto Scaling groups in the Console, you are presented with four options to define the replacement behavior of your instance maintenance policy. These options include the No policy option, which allows you to maintain the default instance replacement settings that the Amazon EC2 Auto Scaling service uses today.

The GUI for the instance maintenance policy feature within the “Create Auto Scaling group” wizard.

Image 1: The GUI for the instance maintenance policy feature within the “Create Auto Scaling group” wizard.

Using instance maintenance policy to increase application availability

The Launch before terminating policy is the right selection when you want to favor availability of your Amazon EC2 Auto Scaling group capacity. This policy setting temporarily increases the group’s capacity by launching new instances during replacement operations. In the Amazon EC2 console, you select the Launch before terminating replacement behavior, and then set your desired MaxHealthyPercentage value to determine how many more instances should be launched during instance replacement.

For example, if you are managing a workload that requires optimal availability during instance replacements, choose the Launch before terminating policy type with a MinHealthyPercentage set to 100%. If you set your MaxHealthyPercentage to 150%, then Amazon EC2 Auto Scaling launches replacement instances before terminating instances to be replaced. You should see the desired capacity increase by 50%, exceeding the group maximum capacity during the operation to provide you with the needed availability. The chart in the following figure illustrates what an instance refresh operation would behave like with a Launch before terminating policy.

A graph simulating the instance replacement process with a policy configured to launch before terminating.

Figure 1: A graph simulating the instance replacement process with a policy configured to launch before terminating.

Overriding a group’s instance maintenance policy during instance refresh

Instance maintenance policy settings apply to all instance replacement operations, but they can be overridden at the start of a new instance refresh operation. Overriding instance maintenance policy is helpful in situations like a bad code deployment that needs replacing without downtime. You could configure an instance maintenance policy to bring an entirely new group’s worth of instances into service before terminating the instances with the problematic code. In this situation, you set the MaxHealthyPercentage to 200% for the instance refresh operation and the replacement happens in a single cycle to promptly address the bad code issue. Setting the MaxHealthyPercentage to 200% will allow the replacement settings to breach the Auto Scaling Group’s Max capacity value, but would be constrained by any account level quotas, so be sure to factor these into application of this feature. See the following figure for a visualization of how this operation would behave.

A graph simulating the instance replacement process with a policy configured to accelerate a new deployment.

Figure 2: A graph simulating the instance replacement process with a policy configured to accelerate a new deployment.

Controlling costs during replacements and deployments

The Terminate and launch policy option allows you to favor cost control during instance replacement. By configuring this policy type, Amazon EC2 Auto Scaling terminates existing instances and then launches new instances during the replacement process. To set a Terminate and launch policy, you must specify a MinHealthyPercentage to establish how low the capacity can drop, and keep your MaxHealthyPercentage set to 100%. This configuration keeps the Auto Scaling group’s capacity at or below the desired capacity setting.

The following figure shows behavior with the MinHealthyPercentage set to 80%. During the instance replacement process, the Auto Scaling group first terminates 20% of the instances and immediately launches replacement instances, temporarily reducing the group’s healthy capacity to 80%. The group waits for the new instances to pass its configured health checks and complete warm up before it moves on to replacing the remaining batches of instances.

: A graph simulating the instance replacement process with a policy configured to terminate and launch.

Figure 3: A graph simulating the instance replacement process with a policy configured to terminate and launch.

Note that the difference between MinHealthyPercentage and MaxHealthyPercentage values impacts the speed of the instance replacement process. In the preceding figure, the Amazon EC2 Auto Scaling group replaces 20% of the instances in each cycle. The larger the gap between the MinHealthyPercentage and MaxHealthyPercentage, the faster the replacement process.

Using a custom policy for maximum flexibility

You can also choose to adopt a Custom behavior option, where you have the flexibility to set the MinHealthyPercentage and MinHealthyPercentage values to whatever you choose. Using this policy type allows you to fine-tune the replacement behavior and control the capacity of your instances within the Amazon EC2 Auto Scaling group to tailor the instance maintenance policy to meet your unique needs.

What about fractional replacement calculations?

Amazon EC2 Auto Scaling always favors availability when performing instance replacements. When instance maintenance policy is configured, Amazon EC2 Auto Scaling also prioritizes launching a new instance rather than going below the MinHealthyPercentage. For example, in an Amazon EC2 Auto Scaling group with a desired capacity of 10 instances and an instance maintenance policy with MinHealthyPercentage set to 99% and MaxHealthyPercentage set to 100%, your settings do not allow for a reduction in capacity of at least one instance. Therefore, Amazon EC2 Auto Scaling biases toward launch before terminating and launches one new instance before terminating any instances that need replacing.

Configuring an instance maintenance policy is not mandatory. If you don’t configure your Amazon EC2 Auto Scaling groups to use an instance maintenance policy, then there is no change in the behavior of your Amazon EC2 Auto Scaling groups’ existing instance replacement process.

You can set a group-level instance maintenance policy through your CloudFormation or Terraform templates. Within your templates, you must set values for both the MinHealthyPercentage and MaxHealthyPercentage settings to determine the instance replacement behavior that aligns with the specific requirements of your Amazon EC2 Auto Scaling group.

Conclusion

In this post, we introduced the new instance maintenance policy feature for Amazon EC2 Auto Scaling groups, explored its capabilities, and provided examples of how to use this new feature. Instance maintenance policy settings apply to all instance replacement processes with the option to override the settings on a per instance refresh basis. By configuring instance maintenance policies, you can control the launch and lifecycle of instances in your Amazon EC2 Auto Scaling groups, increase application availability, reduce manual intervention, and improve cost control for your Amazon EC2 usage.

To learn more about the feature and how to get started, refer to the Amazon EC2 Auto Scaling User Guide.

Writing IAM Policies: Grant Access to User-Specific Folders in an Amazon S3 Bucket

Post Syndicated from Dylan Souvage original https://aws.amazon.com/blogs/security/writing-iam-policies-grant-access-to-user-specific-folders-in-an-amazon-s3-bucket/

November 14, 2023: We’ve updated this post to use IAM Identity Center and follow updated IAM best practices.

In this post, we discuss the concept of folders in Amazon Simple Storage Service (Amazon S3) and how to use policies to restrict access to these folders. The idea is that by properly managing permissions, you can allow federated users to have full access to their respective folders and no access to the rest of the folders.

Overview

Imagine you have a team of developers named Adele, Bob, and David. Each of them has a dedicated folder in a shared S3 bucket, and they should only have access to their respective folders. These users are authenticated through AWS IAM Identity Center (successor to AWS Single Sign-On).

In this post, you’ll focus on David. You’ll walk through the process of setting up these permissions for David using IAM Identity Center and Amazon S3. Before you get started, let’s first discuss what is meant by folders in Amazon S3, because it’s not as straightforward as it might seem. To learn how to create a policy with folder-level permissions, you’ll walk through a scenario similar to what many people have done on existing files shares, where every IAM Identity Center user has access to only their own home folder. With folder-level permissions, you can granularly control who has access to which objects in a specific bucket.

You’ll be shown a policy that grants IAM Identity Center users access to the same Amazon S3 bucket so that they can use the AWS Management Console to store their information. The policy allows users in the company to upload or download files from their department’s folder, but not to access any other department’s folder in the bucket.

After the policy is explained, you’ll see how to create an individual policy for each IAM Identity Center user.

Throughout the rest of this post, you will use a policy, which will be associated with an IAM Identity Center user named David. Also, you must have already created an S3 bucket.

Note: S3 buckets have a global namespace and you must change the bucket name to a unique name.

For this blog post, you will need an S3 bucket with the following structure (the example bucket name for the rest of the blog is “my-new-company-123456789”):

/home/Adele/
/home/Bob/
/home/David/
/confidential/
/root-file.txt

Figure 1: Screenshot of the root of the my-new-company-123456789 bucket

Figure 1: Screenshot of the root of the my-new-company-123456789 bucket

Your S3 bucket structure should have two folders, home and confidential, with a file root-file.txt in the main bucket directory. Inside confidential you will have no items or folders. Inside home there should be three sub-folders: Adele, Bob, and David.

Figure 2: Screenshot of the home/ directory of the my-new-company-123456789 bucket

Figure 2: Screenshot of the home/ directory of the my-new-company-123456789 bucket

A brief lesson about Amazon S3 objects

Before explaining the policy, it’s important to review how Amazon S3 objects are named. This brief description isn’t comprehensive, but will help you understand how the policy works. If you already know about Amazon S3 objects and prefixes, skip ahead to Creating David in Identity Center.

Amazon S3 stores data in a flat structure; you create a bucket, and the bucket stores objects. S3 doesn’t have a hierarchy of sub-buckets or folders; however, tools like the console can emulate a folder hierarchy to present folders in a bucket by using the names of objects (also known as keys). When you create a folder in S3, S3 creates a 0-byte object with a key that references the folder name that you provided. For example, if you create a folder named photos in your bucket, the S3 console creates a 0-byte object with the key photos/. The console creates this object to support the idea of folders. The S3 console treats all objects that have a forward slash (/) character as the last (trailing) character in the key name as a folder (for example, examplekeyname/)

To give you an example, for an object that’s named home/common/shared.txt, the console will show the shared.txt file in the common folder in the home folder. The names of these folders (such as home/ or home/common/) are called prefixes, and prefixes like these are what you use to specify David’s department folder in his policy. By the way, the slash (/) in a prefix like home/ isn’t a reserved character — you could name an object (using the Amazon S3 API) with prefixes such as home:common:shared.txt or home-common-shared.txt. However, the convention is to use a slash as the delimiter, and the Amazon S3 console (but not S3 itself) treats the slash as a special character for showing objects in folders. For more information on organizing objects in the S3 console using folders, see Organizing objects in the Amazon S3 console by using folders.

Creating David in Identity Center

IAM Identity Center helps you securely create or connect your workforce identities and manage their access centrally across AWS accounts and applications. Identity Center is the recommended approach for workforce authentication and authorization on AWS for organizations of any size and type. Using Identity Center, you can create and manage user identities in AWS, or connect your existing identity source, including Microsoft Active Directory, Okta, Ping Identity, JumpCloud, Google Workspace, and Azure Active Directory (Azure AD). For further reading on IAM Identity Center, see the Identity Center getting started page.

Begin by setting up David as an IAM Identity Center user. To start, open the AWS Management Console and go to IAM Identity Center and create a user.

Note: The following steps are for Identity Center without System for Cross-domain Identity Management (SCIM) turned on, the add user option won’t be available if SCIM is turned on.

  1. From the left pane of the Identity Center console, select Users, and then choose Add user.
    Figure 3: Screenshot of IAM Identity Center Users page.

    Figure 3: Screenshot of IAM Identity Center Users page.

  2. Enter David as the Username, enter an email address that you have access to as you will need this later to confirm your user, and then enter a First name, Last name, and Display name.
  3. Leave the rest as default and choose Add user.
  4. Select Users from the left navigation pane and verify you’ve created the user David.
    Figure 4: Screenshot of adding users to group in Identity Center.

    Figure 4: Screenshot of adding users to group in Identity Center.

  5. Now that you’re verified the user David has been created, use the left pane to navigate to Permission sets, then choose Create permission set.
    Figure 5: Screenshot of permission sets in Identity Center.

    Figure 5: Screenshot of permission sets in Identity Center.

  6. Select Custom permission set as your Permission set type, then choose Next.
    Figure 6: Screenshot of permission set types in Identity Center.

    Figure 6: Screenshot of permission set types in Identity Center.

David’s policy

This is David’s complete policy, which will be associated with an IAM Identity Center federated user named David by using the console. This policy grants David full console access to only his folder (/home/David) and no one else’s. While you could grant each user access to their own bucket, keep in mind that an AWS account can have up to 100 buckets by default. By creating home folders and granting the appropriate permissions, you can instead allow thousands of users to share a single bucket.

{
 “Version”:”2012-10-17”,
 “Statement”: [
   {
     “Sid”: “AllowUserToSeeBucketListInTheConsole”,
     “Action”: [“s3:ListAllMyBuckets”, “s3:GetBucketLocation”],
     “Effect”: “Allow”,
     “Resource”: [“arn:aws:s3:::*”]
   },
  {
     “Sid”: “AllowRootAndHomeListingOfCompanyBucket”,
     “Action”: [“s3:ListBucket”],
     “Effect”: “Allow”,
     “Resource”: [“arn:aws:s3::: my-new-company-123456789”],
     “Condition”:{“StringEquals”:{“s3:prefix”:[“”,”home/”, “home/David”],”s3:delimiter”:[“/”]}}
    },
   {
     “Sid”: “AllowListingOfUserFolder”,
     “Action”: [“s3:ListBucket”],
     “Effect”: “Allow”,
     “Resource”: [“arn:aws:s3:::my-new-company-123456789”],
     “Condition”:{“StringLike”:{“s3:prefix”:[“home/David/*”]}}
   },
   {
     “Sid”: “AllowAllS3ActionsInUserFolder”,
     “Effect”: “Allow”,
     “Action”: [“s3:*”],
     “Resource”: [“arn:aws:s3:::my-new-company-123456789/home/David/*”]
   }
 ]
}
  1. Now, copy and paste the preceding IAM Policy into the inline policy editor. In this case, you use the JSON editor. For information on creating policies, see Creating IAM policies.
    Figure 7: Screenshot of the inline policy inside the permissions set in Identity Center.

    Figure 7: Screenshot of the inline policy inside the permissions set in Identity Center.

  2. Give your permission set a name and a description, then leave the rest at the default settings and choose Next.
  3. Verify that you modify the policies to have the bucket name you created earlier.
  4. After your permission set has been created, navigate to AWS accounts on the left navigation pane, then select Assign users or groups.
    Figure 8: Screenshot of the AWS accounts in Identity Center.

    Figure 8: Screenshot of the AWS accounts in Identity Center.

  5. Select the user David and choose Next.
    Figure 9: Screenshot of the AWS accounts in Identity Center.

    Figure 9: Screenshot of the AWS accounts in Identity Center.

  6. Select the permission set you created earlier, choose Next, leave the rest at the default settings and choose Submit.
    Figure 10: Screenshot of the permission sets in Identity Center.

    Figure 10: Screenshot of the permission sets in Identity Center.

    You’ve now created and attached the permissions required for David to view his S3 bucket folder, but not to view the objects in other users’ folders. You can verify this by signing in as David through the AWS access portal.

    Figure 11: Screenshot of the settings summary in Identity Center.

    Figure 11: Screenshot of the settings summary in Identity Center.

  7. Navigate to the dashboard in IAM Identity Center and go to the Settings summary, then choose the AWS access portal URL.
    Figure 12: Screenshot of David signing into the console via the Identity Center dashboard URL.

    Figure 12: Screenshot of David signing into the console via the Identity Center dashboard URL.

  8. Sign in as the user David with the one-time password you received earlier when creating David.
    Figure 13: Second screenshot of David signing into the console through the Identity Center dashboard URL.

    Figure 13: Second screenshot of David signing into the console through the Identity Center dashboard URL.

  9. Open the Amazon S3 console.
  10. Search for the bucket you created earlier.
    Figure 14: Screenshot of my-new-company-123456789 bucket in the AWS console.

    Figure 14: Screenshot of my-new-company-123456789 bucket in the AWS console.

  11. Navigate to David’s folder and verify that you have read and write access to the folder. If you navigate to other users’ folders, you’ll find that you don’t have access to the objects inside their folders.

David’s policy consists of four blocks; let’s look at each individually.

Block 1: Allow required Amazon S3 console permissions

Before you begin identifying the specific folders David can have access to, you must give him two permissions that are required for Amazon S3 console access: ListAllMyBuckets and GetBucketLocation.

   {
      "Sid": "AllowUserToSeeBucketListInTheConsole",
      "Action": ["s3:GetBucketLocation", "s3:ListAllMyBuckets"],
      "Effect": "Allow",
      "Resource": ["arn:aws:s3:::*"]
   }

The ListAllMyBuckets action grants David permission to list all the buckets in the AWS account, which is required for navigating to buckets in the Amazon S3 console (and as an aside, you currently can’t selectively filter out certain buckets, so users must have permission to list all buckets for console access). The console also does a GetBucketLocation call when users initially navigate to the Amazon S3 console, which is why David also requires permission for that action. Without these two actions, David will get an access denied error in the console.

Block 2: Allow listing objects in root and home folders

Although David should have access to only his home folder, he requires additional permissions so that he can navigate to his folder in the Amazon S3 console. David needs permission to list objects at the root level of the my-new-company-123456789 bucket and to the home/ folder. The following policy grants these permissions to David:

   {
      "Sid": "AllowRootAndHomeListingOfCompanyBucket",
      "Action": ["s3:ListBucket"],
      "Effect": "Allow",
      "Resource": ["arn:aws:s3:::my-new-company-123456789"],
      "Condition":{"StringEquals":{"s3:prefix":["","home/", "home/David"],"s3:delimiter":["/"]}}
   }

Without the ListBucket permission, David can’t navigate to his folder because he won’t have permissions to view the contents of the root and home folders. When David tries to use the console to view the contents of the my-new-company-123456789 bucket, the console will return an access denied error. Although this policy grants David permission to list all objects in the root and home folders, he won’t be able to view the contents of any files or folders except his own (you specify these permissions in the next block).

This block includes conditions, which let you limit under what conditions a request to AWS is valid. In this case, David can list objects in the my-new-company-123456789 bucket only when he requests objects without a prefix (objects at the root level) and objects with the home/ prefix (objects in the home folder). If David tries to navigate to other folders, such as confidential/, David is denied access. Additionally, David needs permissions to list prefix home/David to be able to use the search functionality of the console instead of scrolling down the list of users’ folders.

To set these root and home folder permissions, I used two conditions: s3:prefix and s3:delimiter. The s3:prefix condition specifies the folders that David has ListBucket permissions for. For example, David can list the following files and folders in the my-new-company-123456789 bucket:

/root-file.txt
/confidential/
/home/Adele/
/home/Bob/
/home/David/

But David cannot list files or subfolders in the confidential/, home/Adele, or home/Bob folders.

Although the s3:delimiter condition isn’t required for console access, it’s still a good practice to include it in case David makes requests by using the API. As previously noted, the delimiter is a character—such as a slash (/)—that identifies the folder that an object is in. The delimiter is useful when you want to list objects as if they were in a file system. For example, let’s assume the my-new-company-123456789 bucket stored thousands of objects. If David includes the delimiter in his requests, he can limit the number of returned objects to just the names of files and subfolders in the folder he specified. Without the delimiter, in addition to every file in the folder he specified, David would get a list of all files in any subfolders.

Block 3: Allow listing objects in David’s folder

In addition to the root and home folders, David requires access to all objects in the home/David/ folder and any subfolders that he might create. Here’s a policy that allows this:

{
      “Sid”: “AllowListingOfUserFolder”,
      “Action”: [“s3:ListBucket”],
      “Effect”: “Allow”,
      “Resource”: [“arn:aws:s3:::my-new-company-123456789”],
      "Condition":{"StringLike":{"s3:prefix":["home/David/*"]}}
    }

In the condition above, you use a StringLike expression in combination with the asterisk (*) to represent an object in David’s folder, where the asterisk acts as a wildcard. That way, David can list files and folders in his folder (home/David/). You couldn’t include this condition in the previous block (AllowRootAndHomeListingOfCompanyBucket) because it used the StringEquals expression, which would interpret the asterisk (*) as an asterisk, not as a wildcard.

In the next section, the AllowAllS3ActionsInUserFolder block, you’ll see that the Resource element specifies my-new-company/home/David/*, which looks like the condition that I specified in this section. You might think that you can similarly use the Resource element to specify David’s folder in this block. However, the ListBucket action is a bucket-level operation, meaning the Resource element for the ListBucket action applies only to bucket names and doesn’t take folder names into account. So, to limit actions at the object level (files and folders), you must use conditions.

Block 4: Allow all Amazon S3 actions in David’s folder

Finally, you specify David’s actions (such as read, write, and delete permissions) and limit them to just his home folder, as shown in the following policy:

    {
      "Sid": "AllowAllS3ActionsInUserFolder",
      "Effect": "Allow",
      "Action": ["s3:*"],
      "Resource": ["arn:aws:s3:::my-new-company-123456789/home/David/*"]
    }

For the Action element, you specified s3:*, which means David has permission to do all Amazon S3 actions. In the Resource element, you specified David’s folder with an asterisk (*) (a wildcard) so that David can perform actions on the folder and inside the folder. For example, David has permission to change his folder’s storage class. David also has permission to upload files, delete files, and create subfolders in his folder (perform actions in the folder).

An easier way to manage policies with policy variables

In David’s folder-level policy you specified David’s home folder. If you wanted a similar policy for users like Bob and Adele, you’d have to create separate policies that specify their home folders. Instead of creating individual policies for each IAM Identity Center user, you can use policy variables and create a single policy that applies to multiple users (a group policy). Policy variables act as placeholders. When you make a request to a service in AWS, the placeholder is replaced by a value from the request when the policy is evaluated.

For example, you can use the previous policy and replace David’s user name with a variable that uses the requester’s user name through attributes and PrincipalTag as shown in the following policy (copy this policy to use in the procedure that follows):

{
	"Version": "2012-10-17",
	"Statement": [
		{
			"Sid": "AllowUserToSeeBucketListInTheConsole",
			"Action": [
				"s3:ListAllMyBuckets",
				"s3:GetBucketLocation"
			],
			"Effect": "Allow",
			"Resource": [
				"arn:aws:s3:::*"
			]
		},
		{
			"Sid": "AllowRootAndHomeListingOfCompanyBucket",
			"Action": [
				"s3:ListBucket"
			],
			"Effect": "Allow",
			"Resource": [
				"arn:aws:s3:::my-new-company-123456789"
			],
			"Condition": {
				"StringEquals": {
					"s3:prefix": [
						"",
						"home/",
						"home/${aws:PrincipalTag/userName}"
					],
					"s3:delimiter": [
						"/"
					]
				}
			}
		},
		{
			"Sid": "AllowListingOfUserFolder",
			"Action": [
				"s3:ListBucket"
			],
			"Effect": "Allow",
			"Resource": [
				"arn:aws:s3:::my-new-company-123456789"
			],
			"Condition": {
				"StringLike": {
					"s3:prefix": [
						"home/${aws:PrincipalTag/userName}/*"
					]
				}
			}
		},
		{
			"Sid": "AllowAllS3ActionsInUserFolder",
			"Effect": "Allow",
			"Action": [
				"s3:*"
			],
			"Resource": [
				"arn:aws:s3:::my-new-company-123456789/home/${aws:PrincipalTag/userName}/*"
			]
		}
	]
}
  1. To implement this policy with variables, begin by opening the IAM Identity Center console using the main AWS admin account (ensuring you’re not signed in as David).
  2. Select Settings on the left-hand side, then select the Attributes for access control tab.
    Figure 15: Screenshot of Settings inside Identity Center.

    Figure 15: Screenshot of Settings inside Identity Center.

  3. Create a new attribute for access control, entering userName as the Key and ${path:userName} as the Value, then choose Save changes. This will add a session tag to your Identity Center user and allow you to use that tag in an IAM policy.
    Figure 16: Screenshot of managing attributes inside Identity Center settings.

    Figure 16: Screenshot of managing attributes inside Identity Center settings.

  4. To edit David’s permissions, go back to the IAM Identity Center console and select Permission sets.
    Figure 17: Screenshot of permission sets inside Identity Center with Davids-Permissions selected.

    Figure 17: Screenshot of permission sets inside Identity Center with Davids-Permissions selected.

  5. Select David’s permission set that you created previously.
  6. Select Inline policy and then choose Edit to update David’s policy by replacing it with the modified policy that you copied at the beginning of this section, which will resolve to David’s username.
    Figure 18: Screenshot of David’s policy inside his permission set inside Identity Center.

    Figure 18: Screenshot of David’s policy inside his permission set inside Identity Center.

You can validate that this is set up correctly by signing in to David’s user through the Identity Center dashboard as you did before and verifying you have access to the David folder and not the Bob or Adele folder.

Figure 19: Screenshot of David’s S3 folder with access to a .jpg file inside.

Figure 19: Screenshot of David’s S3 folder with access to a .jpg file inside.

Whenever a user makes a request to AWS, the variable is replaced by the user name of whoever made the request. For example, when David makes a request, ${aws:PrincipalTag/userName} resolves to David; when Adele makes the request, ${aws:PrincipalTag/userName} resolves to Adele.

It’s important to note that, if this is the route you use to grant access, you must control and limit who can set this username tag on an IAM principal. Anyone who can set this tag can effectively read/write to any of these bucket prefixes. It’s important that you limit access and protect the bucket prefixes and who can set the tags. For more information, see What is ABAC for AWS, and the Attribute-based access control User Guide.

Conclusion

By using Amazon S3 folders, you can follow the principle of least privilege and verify that the right users have access to what they need, and only to what they need.

See the following example policy that only allows API access to the buckets, and only allows for adding, deleting, restoring, and listing objects inside the folders:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "AllowAllS3ActionsInUserFolder",
            "Effect": "Allow",
            "Action": [
                "s3:DeleteObject",
                "s3:DeleteObjectTagging",
                "s3:DeleteObjectVersion",
                "s3:DeleteObjectVersionTagging",
                "s3:GetObject",
                "s3:GetObjectTagging",
                "s3:GetObjectVersion",
                "s3:GetObjectVersionTagging",
                "s3:ListBucket",
                "s3:PutObject",
                "s3:PutObjectTagging",
                "s3:PutObjectVersionTagging",
                "s3:RestoreObject"
            ],
            "Resource": [
		   "arn:aws:s3:::my-new-company-123456789",
                "arn:aws:s3:::my-new-company-123456789/home/${aws:PrincipalTag/userName}/*"
            ],
            "Condition": {
                "StringLike": {
                    "s3:prefix": [
                        "home/${aws:PrincipalTag/userName}/*"
                    ]
                }
            }
        }
    ]
}

We encourage you to think about what policies your users might need and restrict the access by only explicitly allowing what is needed.

Here are some additional resources for learning about Amazon S3 folders and about IAM policies, and be sure to get involved at the community forums:

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Dylan Souvage

Dylan Souvage

Dylan is a Solutions Architect based in Toronto, Canada. Dylan loves working with customers to understand their business needs and enable them in their cloud journey. In his spare time, he enjoys going out in nature, going on long road trips, and traveling to warm, sunny places.

Abhra Sinha

Abhra Sinha

Abhra is a Toronto-based Senior Solutions Architect at AWS. Abhra enjoys being a trusted advisor to customers, working closely with them to solve their technical challenges and help build a secure scalable architecture on AWS. In his spare time, he enjoys Photography and exploring new restaurants.

Divyajeet Singh

Divyajeet Singh

Divyajeet (DJ) is a Sr. Solutions Architect at AWS Canada. He loves working with customers to help them solve their unique business challenges using the cloud. In his free time, he enjoys spending time with family and friends, and exploring new places.

An Overview of Bulk Sender Changes at Yahoo/Gmail

Post Syndicated from Dustin Taylor original https://aws.amazon.com/blogs/messaging-and-targeting/an-overview-of-bulk-sender-changes-at-yahoo-gmail/

In a move to safeguard user inboxes, Gmail and Yahoo Mail announced a new set of requirements for senders effective from February 2024. Let’s delve into the specifics and what Amazon Simple Email Service (Amazon SES) customers need to do to comply with these requirements.

What are the new email sender requirements?

The new requirements include long-standing best practices that all email senders should adhere to in order to achieve good deliverability with mailbox providers. What’s new is that Gmail, Yahoo Mail, and other mailbox providers will require alignment with these best practices for those who send bulk messages over 5000 per day or if a significant number of recipients indicate the mail as spam.

The requirements can be distilled into 3 categories: 1) stricter adherence to domain authentication, 2) give recipients an easy way to unsubscribe from bulk mail, and 3) monitoring spam complaint rates and keeping them under a 0.3% threshold.

* This blog was originally published in November 2023, and updated on January 12, 2024 to clarify timelines, and to provide links to additional resources.

1. Domain authentication

Mailbox providers will require domain-aligned authentication with DKIM and SPF, and they will be enforcing DMARC policies for the domain used in the From header of messages. For example, gmail.com will be publishing a quarantine DMARC policy, which means that unauthorized messages claiming to be from Gmail will be sent to Junk folders.

Read Amazon SES: Email Authentication and Getting Value out of Your DMARC Policy to gain a deeper understanding of SPF and DKIM domain-alignment and maximize the value from your domain’s DMARC policy.

The following steps outline how Amazon SES customers can adhere to the domain authentication requirements:

Adopt domain identities: Amazon SES customers who currently rely primarily on email address identities will need to adopt verified domain identities to achieve better deliverability with mailbox providers. By using a verified domain identity with SES, your messages will have a domain-aligned DKIM signature.

Not sure what domain to use? Read Choosing the Right Domain for Optimal Deliverability with Amazon SES for additional best practice guidance regarding sending authenticated email. 

Configure a Custom MAIL FROM domain: To further align with best practices, SES customers should also configure a custom MAIL FROM domain so that SPF is domain-aligned.

The table below illustrates the three scenarios based on the type of identity you use with Amazon SES

Scenarios using example.com in the From header DKIM authenticated identifier SPF authenticated identifier DMARC authentication results
[email protected] as a verified email address identity amazonses.com email.amazonses.com Fail – DMARC analysis fails as the sending domain does not have a DKIM signature or SPF record that matches.
example.com as a verified domain identity example.com email.amazonses.com Success – DKIM signature aligns with sending domain which will cause DMARC checks to pass.
example.com as a verified domain identity, and bounce.example.com as a custom MAIL FROM domain example.com bounce.example.com Success – DKIM and SPF are aligned with sending domain.

Figure 1: Three scenarios based on the type of identity used with Amazon SES. Using a verified domain identity and configuring a custom MAIL FROM domain will result in both DKIM and SPF being aligned to the From header domain’s DMARC policy.

Be strategic with subdomains: Amazon SES customers should consider a strategic approach to the domains and subdomains used in the From header for different email sending use cases. For example, use the marketing.example.com verified domain identity for sending marketing mail, and use the receipts.example.com verified domain identity to send transactional mail.

Why? Marketing messages may have higher spam complaint rates and would need to adhere to the bulk sender requirements, but transactional mail, such as purchase receipts, would not necessarily have spam complaints high enough to be classified as bulk mail.

Publish DMARC policies: Publish a DMARC policy for your domain(s). The domain you use in the From header of messages needs to have a policy by setting the p= tag in the domain’s DMARC policy in DNS. The policy can be set to “p=none” to adhere to the bulk sending requirements and can later be changed to quarantine or reject when you have ensured all email using the domain is authenticated with DKIM or SPF domain-aligned authenticated identifiers.

2. Set up an easy unsubscribe for email recipients

Bulk senders are expected to include a mechanism to unsubscribe by adding an easy to find link within the message. The February 2024 mailbox provider rules will require senders to additionally add one-click unsubscribe headers as defined by RFC 2369 and RFC 8058. These headers make it easier for recipients to unsubscribe, which reduces the rate at which recipients will complain by marking messages as spam.

There are many factors that could result in your messages being classified as bulk by any mailbox provider. Volume over 5000 per day is one factor, but the primary factor that mailbox providers use is in whether the recipient actually wants to receive the mail.

If you aren’t sure if your mail is considered bulk, monitor your spam complaint rates. If the complaint rates are high or growing, it is a sign that you should offer an easy way for recipients to unsubscribe.

How to adhere to the easy unsubscribe requirement

The following steps outline how Amazon SES customers can adhere to the easy unsubscribe requirement:

Add one-click unsubscribe headers to the messages you send: Amazon SES customers sending bulk or potentially unwanted messages will need to implement an easy way for recipients to unsubscribe, which they can do using the SES subscription management feature.

Mailbox providers are requiring that large senders give recipients the ability to unsubscribe from bulk email in one click using the one-click unsubscribe header, however it is acceptable for the unsubscribe link in the message to direct the recipient to a landing page for the recipient to confirm their opt-out preferences.

To set up one-click unsubscribe without using the SES subscription management feature, include both of these headers in outgoing messages:

  • List-Unsubscribe-Post: List-Unsubscribe=One-Click
  • List-Unsubscribe: <https://example.com/unsubscribe/example>

When a recipient unsubscribes using one-click, you receive this POST request:

POST /unsubscribe/example HTTP/1.1
Host: example.com
Content-Type: application/x-www-form-urlencoded
Content-Length: 26
List-Unsubscribe=One-Click

Gmail’s FAQ and Yahoo’s FAQ both clarify that the one-click unsubscribe requirement will not be enforced until June 2024 as long as the bulk sender has a functional unsubscribe link clearly visible in the footer of each message.

Honor unsubscribe requests within 2 days: Verify that your unsubscribe process immediately removes the recipient from receiving similar future messages. Mailbox providers are requiring that bulk senders give recipients the ability to unsubscribe from email in one click, and that the senders process unsubscribe requests within two days.

If you adopt the SES subscription management feature, make sure you integrate the recipient opt-out preferences with the source of your email sending lists. If you implement your own one-click unsubscribe (for example, using Amazon API Gateway and an AWS Lambda function), make sure it designed to suppress sending to email addresses in your source email lists.

Review your email list building practices: Ensure responsible email practices by refraining from purchasing email lists, safeguarding opt-in forms from bot abuse, verifying recipients’ preferences through confirmation messages, and abstaining from automatically enrolling recipients in categories that were not requested.

Having good list opt-in hygiene is the best way to ensure that you don’t have high spam complaint rates before you adhere to the new required best practices. To learn more, read What is a Spam Trap, and Why You Should Care.

3. Monitor spam rates

Mailbox providers will require that all senders keep spam complaint rates below 0.3% to avoid having their email treated as spam by the mailbox provider. The following steps outline how Amazon SES customers can meet the spam complaint rate requirement:

Enroll with Google Postmaster Tools: Amazon SES customers should enroll with Google Postmaster Tools to monitor their spam complaint rates for Gmail recipients.

Gmail recommends spam complaint rates stay below 0.1%. If you send to a mix of Gmail recipients and recipients on other mailbox providers, the spam complaint rates reported by Gmail’s Postmaster Tools are a good indicator of your spam complaint rates at mailbox providers who don’t let you view metrics.

Enable Amazon SES Virtual Deliverability Manager: Enable Virtual Deliverability Manager (VDM) in your Amazon SES account. Customers can use VDM to monitor bounce and complaint rates for many mailbox providers. Amazon SES recommends customers to monitor reputation metrics and stay below a 0.1% complaint rate.

Segregate and secure your sending using configuration sets: In addition to segregating sending use cases by domain, Amazon SES customers should use configuration sets for each sending use case.

Using configuration sets will allow you to monitor your sending activity and implement restrictions with more granularity. You can even pause the sending of a configuration set automatically if spam complaint rates exceed your tolerance threshold.

Conclusion

These changes are planned for February 2024, but be aware that the exact timing and methods used by each mailbox provider may vary. If you experience any deliverability issues with any mailbox provider prior to February, it is in your best interest to adhere to these required best practices as a first step.

We hope that this blog clarifies any areas of confusion on this change and provides you with the information you need to be prepared for February 2024. Happy sending!

Helpful links:

Implement fine-grained access control in Amazon SageMaker Studio and Amazon EMR using Apache Ranger and Microsoft Active Directory

Post Syndicated from Rahul Sarda original https://aws.amazon.com/blogs/big-data/implement-fine-grained-access-control-in-amazon-sagemaker-studio-and-amazon-emr-using-apache-ranger-and-microsoft-active-directory/

Amazon SageMaker Studio is a fully integrated development environment (IDE) for machine learning (ML) that enables data scientists and developers to perform every step of the ML workflow, from preparing data to building, training, tuning, and deploying models. SageMaker Studio comes with built-in integration with Amazon EMR, enabling data scientists to interactively prepare data at petabyte scale using frameworks such as Apache Spark, Hive, and Presto right from SageMaker Studio notebooks. With Amazon SageMaker, developers, data scientists, and SageMaker Studio users can access both raw data stored in Amazon Simple Storage Service (Amazon S3), and cataloged tabular data stored in a Hive metastore easily. SageMaker Studio’s support for Apache Ranger creates a simple mechanism for applying fine-grained access control to the raw and cataloged data with grant and revoke policies administered from a friendly web interface.

In this post, we show how you can authenticate into SageMaker Studio using an existing Active Directory (AD), with authorized access to both Amazon S3 and Hive cataloged data using AD entitlements via Apache Ranger integration and AWS IAM Identity Center (successor to AWS Single Sign-On). With this solution, you can manage access to multiple SageMaker environments and SageMaker Studio notebooks using a single set of credentials. Subsequently, Apache Spark jobs created from SageMaker Studio notebooks will access only the data and resources permitted by Apache Ranger policies attached to the AD credentials, inclusive of table and column-level access.

With this capability, multiple SageMaker Studio users can connect to the same EMR cluster, gaining access only to data granted to their user or group, with audit records captured and visible in Amazon CloudWatch. This multi-tenant environment is possible through user session isolation that prevents users from accessing datasets and cluster resources allocated to other users. Ultimately, organizations can provision fewer clusters, reduce administrative overhead, and increase cluster utilization, saving staff time and cloud costs.

Solution overview

We demonstrate this solution with an end-to-end use case using a sample ecommerce dataset. The dataset is available within provided AWS CloudFormation templates and consists of transactional ecommerce data (products, orders, customers) cataloged in a Hive metastore.

The solution utilizes two data analyst personas, Alex and Tina, each tasked with different analysis requiring fine-grained limitations on dataset access:

  • Tina, a data scientist on the marketing team, is tasked with building a model for customer lifetime value. Data access should only be permitted to non-sensitive customer, product, and orders data.
  • Alex, a data scientist on the sales team, is tasked to generate product demand forecast, requiring access to product and orders data. No customer data is required.

The following figure illustrates our desired fine-grained access.

The following diagram illustrates the solution architecture.

The architecture is implemented as follows:

  • Microsoft Active Directory – Used to manage user authentication, select AWS application access, and user and group membership for Apache Ranger secured data authorization
  • Apache Ranger – Used to monitor and manage comprehensive data security across the Hadoop and Amazon EMR platform
  • Amazon EMR – Used to retrieve, prepare, and analyze data from the Hive metastore using Spark
  • SageMaker Studio – An integrated IDE with purpose-built tools to build AI/ML models.

The following sections walk through the setup of the architectural components for this solution using the CloudFormation stack.

Prerequisites

Before you get started, make sure you have the following prerequisites:

Create resources with AWS CloudFormation

To build the solution within your environment, use the provided CloudFormation templates to create the required AWS resources.

Note that running these CloudFormation templates and the following configuration steps will create AWS resources that may incur charges. Additionally, all the steps should be run in the same Region.

Template 1

This first template creates the following resources and takes approximately 15 minutes to complete:

  • A Multi-AZ, multi-subnet VPC infrastructure, with managed NAT gateways in the public subnet for each Availability Zone
  • S3 VPC endpoints and Elastic Network Interfaces
  • A Windows Active Directory domain controller using Amazon Elastic Compute Cloud (Amazon EC2) with cross-realm trust
  • A Linux Bastion host (Amazon EC2) in an auto scaling group

To deploy this template, complete the following steps:

  1. Sign in to the AWS Management Console.
  2. On the Amazon EC2 console, create an EC2 key pair.
  3. Choose Launch Stack :
  4. Select the target Region
  5. Verify the stack name and provide the following parameters:
    1. The name of the key pair you created.
    2. Passwords for cross-realm trust, the Windows domain admin, LDAP bind, and default AD user. Be sure to record these passwords to use in future steps.
    3. Select a minimum of three Availability Zones based on the chosen Region.
  6. Review the remaining parameters. No changes are required for the solution, but you may change parameter values if desired.
  7. Choose Next and then choose Next again.
  8. Review the parameters.
  9. Select I acknowledge that AWS CloudFormation might create IAM resources with custom names and I acknowledge that AWS CloudFormation might require the following capability: CAPABILITY_AUTO_EXPAND.
  10. Choose Submit.

Template 2

The second template creates the following resources and takes approximately 30–60 minutes to complete:

To deploy this template, complete the following steps:

  1. Choose Launch Stack :
  2. Select the target Region
  3. Verify the stack name and provide the following parameters:
    1. Key pair name (created earlier).
    2. LDAPHostPrivateIP address, which can be found in the output section of the Windows AD CloudFormation stack.
    3. Passwords for the Windows domain admin, cross-realm trust, AD domain user, and LDAP bind. Use the same passwords as you did for the first CloudFormation template.
    4. Passwords for the RDS for MySQL database and KDC admin. Record these passwords; they may be needed in future steps.
    5. Log directory for the EMR cluster.
    6. VPC (it contains the name of the CloudFormation stack)
    7. Subnet details (align the subnet name with the parameter name).
    8. Set AppsEMR to Hadoop, Spark, Hive, Livy, Hue, and Trino.
    9. Leave RangerAdminPassword as is.
  4. Review the remaining parameters. No changes are required beyond what is mentioned, but you may change parameter values if desired.
  5. Choose Next, then choose Next again.
  6. Review the parameters.
  7. Select I acknowledge that AWS CloudFormation might create IAM resources with custom names and I acknowledge that AWS CloudFormation might require the following capability: CAPABILITY_AUTO_EXPAND.
  8. Choose Submit.

Integrate Active Directory with AWS accounts using IAM Identity Center

To enable users to sign in to SageMaker with Active Directory credentials, a connection between IAM Identity Center and Active Directory must be established.

To connect to Microsoft Active Directory, we set up AWS Directory Service using AD Connector.

  1. On the Directory Service console, choose Directories in the navigation pane.
  2. Choose Set up directory.
  3. For Directory types, select AD Connector.
  4. Choose Next.
  5. For Directory size, select the appropriate size for AD Connector. For this post, we select Small.
  6. Choose Next.
  7. Choose the VPC and private subnets where the Windows AD domain controller resides.
  8. Choose Next.
  9. In the Active Directory information section, enter the following details (this information can be retrieved on the Outputs tab of the first CloudFormation template):
    1. For Directory DNS Name, enter awsemr.com.
    2. For Directory NetBIOS name, enter awsemr.
    3. For DNS IP addresses, enter the IPv4 private IP address from AD Controller.
    4. Enter the service account user name and password that you provided during stack creation.
  10. Choose Next.
  11. Review the settings and choose Create directory.

After the directory is created, you will see its status as Active on the Directory Services console.

Set up AWS Organizations

AWS Organizations supports IAM Identity Center in only one Region at a time. To enable IAM Identity Center in this Region, you must first delete the IAM Identity Center configuration if created in another Region. Do not delete an existing IAM Identity Center configuration unless you are sure it will not negatively impact existing workloads.

  1. Navigate to the IAM Identity Center console.
  2. If IAM Identity Center has not been activated previously, choose Enable. If an organization does not exist, an alert appears to create one.
  3. Choose Create AWS organization.
  4. Choose Settings in the navigation pane.
  5. On the Identity source tab, on the Actions menu, choose Change identity source.
  6. For Choose identity source, select Active Directory.
  7. Choose Next.
  8. For Existing Directories, choose AWSEMR.COM.
  9. Choose Next.
  10. To confirm the change, enter ACCEPT in the confirmation input box, then choose Change identity source. Upon completion, you will be redirected to Settings, where you receive the alert Configurable AD sync paused.
  11. Choose Resume sync.
  12. Choose Settings in the navigation pane.
  13. On the Identity source tab, on the Actions menu, choose Manage sync.
  14. Choose Add users and groups to specify the users and groups to sync from Active Directory to IAM Identity Center.
  15. On the Users tab, enter tina and choose Add.
  16. Enter alex and choose Add.
  17. Choose Submit.
  18. On the Groups tab, enter datascience and choose Add.
  19. Choose Submit.

After your users and groups are synced to IAM Identity Center, you can see them by choosing Users or Groups in the navigation pane on the IAM Identity Center console. When they’re available, you can assign them access to AWS accounts and cloud applications. The initial sync may take up to 5 minutes.

Set up a SageMaker domain using IAM Identity Center

To set up a SageMaker domain, complete the following steps:

  1. On the SageMaker console, choose Domains in the navigation pane.
  2. Choose Create domain.
  3. Choose Standard setup, then choose Configure.
  4. For Domain Name, enter a unique name for your domain.
  5. For Authentication, choose AWS IAM Identity Center.
  6. Choose Create a new role for the default execution role.
  7. In the Create an IAM Role popup, choose Any S3 bucket.
  8. Choose Create role.
  9. Copy the role details to be used in next section for adding a policy for EMR cluster access.
  10. In the Network and storage section, specify the following:
    1. Choose the VPC that you created using the first CloudFormation template.
    2. Choose a private subnet in an Availability Zone supported by SageMaker.
    3. Use the default security group (sg-XXXX).
    4. Choose VPC only.

Note that there is a public domain called AWSEMR.COM that will conflict with the one created for this solution if Public internet only is selected.

  1. Leave all other options as default and choose Next.
  2. In the Studio settings section, accept the defaults and choose Next.
  3. In the RStudio settings section, accept the defaults and choose Next.
  4. In the Canvas setting section, accept the defaults and choose Submit.

Add a policy to provide SageMaker Studio access to the EMR cluster

Complete the following steps to give SageMaker Studio access to the EMR cluster:

  1. On the IAM console, choose Roles in the navigation pane.
  2. Search and choose for the role you copied earlier (<AmazonSageMaker-ExecutionRole- XXXXXXXXXXXXXXX>).
  3. On the Permissions tab, choose Add permissions and Attach policy.
  4. Search for and choose the policy AmazonEMRFullAccessPolicy_v2.
  5. Choose Add permissions.

Add users and groups to access the domain

Complete the following steps to give users and groups access to the domain:

  1. On the SageMaker console, choose Domains in the navigation pane.
  2. Choose the domain you created earlier.
  3. On the Domain details page, choose Assign users and groups.
  4. On the Users tab, select the users tina and alex.
  5. On the Groups tab, select the group datascience.
  6. Choose Assign users and groups.

Configure Spark data access rights in Apache Ranger

Now that the AWS environment is set up, we configure Hive dataset security using Apache Ranger.

To start, collect the Apache Ranger URL details to access the Ranger admin console:

  1. On the Amazon EC2 console, choose Resources in the navigation pane, then Instance (running).
  2. Choose the Ranger server EC2 instance and copy the private IP DNS name (IPv4 only).
    Next, connect to the Windows domain controller to use the connected VPC to access the Ranger admin console. This is done by logging in to the Windows server and launching a web browser.
  3. Install the Remote Desktop Services client on your computer to connect with Windows Server.
  4. Authorize inbound traffic from your computer to the Windows AD domain controller EC2 instance.
  5. On the Amazon EC2 console, choose Resources in the navigation pane, then Instance (running).
  6. Choose on the Windows Domain Controller (DC1) EC2 instance ID and copy the public IP DNS name (IPv4 only).
  7. Use Microsoft Remote Desktop to log in to the Windows domain controller:
    1. Computer – Use the public IP DNS name (IPv4 only).
    2. Username – Enter awsadmin.
    3. Password – Use the password you set during the first CloudFormation template setup.
  8. Disable the Enhanced Security Configuration for Internet Explorer.
  9. Launch Internet Explorer and navigate to the Ranger admin console using the private IP DNS name (IPv4 only) associated with the Ranger server noted earlier and port 6182 (for example, https://<RangerServer Private IP DNS name>:6182).
  10. Choose Continue to this website (not recommended) if you receive a security alert.
  11. Log in using the default user name and password. During the first logon, you should modify your password and store it securely.
  12. In the top Ranger banner, choose Settings and Users/Groups/Roles.
  13. Confirm Tina and Alex are listed as users with a User Source of External.
  14. Confirm the datascience group is listed as a group with Group Source of External.

If the Tina or Alex users aren’t listed, follow the Apache Ranger troubleshooting instructions in the appendix at the end of this post.

Dataset policies

The Apache Ranger access policy model consists of two major components: specification of the resources a policy is applied to, such as files and directories, databases, tables, and columns, services, and so on, and the specification of access conditions (permissions) for specific users and groups.

Configure your dataset policy with the following steps:

  1. On the Ranger admin console, choose the Ranger icon in the top banner to return to the main page.
  2. Choose the service name amazonemrspark inside AMAZON-EMR-SPARK.
  3. Choose Add New Policy and add a new policy with the following parameters:
    1. For Policy Name, enter Data Science Policy.
    2. For Database, enter staging and default.
    3. For EMR Spark Table, enter products and orders.
    4. For EMR Spark Column, enter *.
    5. In the Allow Conditions section, for Select User, enter tina and alex, and for Permissions, enter select and read.
  4. Choose Add.
    When using Internet Explorer & adding a new policy, you may receive the error SCRIPT438: Object doesn't support property or method 'assign'. In this case, install and use an alternate browser such as Firefox or Chrome.
  5. Choose Add New Policy and add a new policy for tina:
    1. For Policy Name, enter Customer Demographics Policy.
    2. For Database, enter staging.
    3. For EMR Spark Table, enter Customers.
    4. For EMR Spark Column, choose customer_id, first_name, last_name, region, and state.
    5. In the Allow Conditions section, for Select User, enter Tina and for Permissions, enter select and read.
  6. Choose Add.

Configure Amazon S3 data access rights in Apache Ranger

Complete the following steps to configure Amazon S3 data access rights:

  1. On the Ranger admin console, choose the Ranger icon in the top banner to return to the main page.
  2. Choose the service name amazonemrs3 inside AMAZON-EMR-EMRFS.
  3. Choose Add New Policy and add a policy for the datascience group as follows:
    1. For Policy Name, enter Data Science S3 Policy.
    2. For S3 resource, enter the following:
      • aws-bigdata-blog/artifacts/aws-blog-emr-ranger/data/staging/products
      • aws-bigdata-blog/artifacts/aws-blog-emr-ranger/data/staging/orders
    3. In the Allow Conditions, section, for Select User, enter tina and alex, and for Permissions, enter GetObject and ListObjects.
  4. Choose Add.
  5. Choose Add New Policy and add a new policy for tina:
    1. For Policy Name, enter Customer Demographics S3 Policy.
    2. For S3 resource, enter aws-bigdata-blog/artifacts/aws-blog-emr-ranger/data/staging/customers.
    3. In the Allow Conditions section, for Select User, enter Tina and for Permissions, enter GetObject and ListObjects.
  6. Choose Add.

Configure Amazon S3 user working folders

While working with data, users often require data storage for interim results. To provide each user with a private working directory, complete the following steps:

  1. On the Ranger admin console, choose Ranger icon in the top banner to return to the main page.
  2. Choose the service name amazonemrs3 inside AMAZON-EMR-EMRFS.
  3. Choose Add New Policy and add a policy for {USER} as follows:
    1. For Policy Name, enter User Directory S3 Policy.
    2. For S3 resource, enter <Bucket Name>/data/{USER} (use a bucket within the account).
    3. Enable Recursive.
    4. In the Allow Conditions, section, for Select User, enter {USER} and for Permissions, enter GetObject, ListObjects, PutObject, and DeleteObject.
  4. Choose Add.

Use the user access login URL

Users attempting to access shared AWS applications via IAM Identity Center need to first log in to the AWS environment with a custom link using their Active Directory user name and password. The link needed can be found on the IAM Identity Center console.

  1. On the IAM Identity Center console, choose Settings in the navigation pane.
  2. On the Identity source tab, locate the user login link under AWS access portal URL.

Test role-based data access

To review, data scientist Tina needs to build a customer lifetime value model, which requires access to orders, product, and non-sensitive customer data. Data scientist Alex only needs access to orders and product data to build a product demand model.

In this section, we test the data access levels for each role.

Data scientist Tina

Complete the following steps:

  1. Log in using the URL you located in the previous step.
  2. Enter Microsoft AD user [email protected] and your password.
  3. Choose the Amazon SageMaker Studio tile.
  4. In the SageMaker Studio UI, start a notebook:
    1. Choose File, New, and Notebook.
    2. For Image, choose SparkMagic.
    3. For Kernel, choose PySpark.
    4. For Instance Type, choose ml.t3.medium.
    5. Choose Select.
  5. When the notebook kernel starts, connect to the EMR cluster by running the following code:
    %load_ext sagemaker_studio_analytics_extension.magics
    %sm_analytics emr connect --cluster-id <EMR Cluster ID> --auth-type Kerberos --language python

The EMR cluster ID details can be found on the Outputs tab of the EMR cluster CloudFormation stack created with the second template.

  1. Enter Microsoft AD [email protected] and your password. (Note that [email protected] is case-sensitive.)
  2. Choose Connect.

Now we can test Tina’s data access.

  1. In a new cell, enter the following query and run the cell:
    %%sql
    show tables from staging

Returned data will indicate the table objects accessible to Tina.

  1. In a new cell, run the following:
    %%sql
    select * from staging.customers limit 5

Returned data will include columns Tina has been granted access.

Let’s test Tina’s access to customer data.

  1. In a new cell, run the following:
    %%sql
    select customer_id, education_level, first_name, last_name, marital_status, region, state from staging.customers limit 15

The preceding query will result in an Access Denied error due to the inclusion of sensitive data columns.

During ad hoc analysis and model building, it’s common for users to create temporary datasets that need to be persisted for a short period. Let’s test Tina’s ability to create a working dataset and store results in a private working directory.

  1. In a new cell, run the following:
    join_order_to_customer = spark.sql("select orders.*, first_name, last_name, region, state from staging.orders, staging.customers where orders.customer_id = customers.customer_id")

  2. Before running the following code, update the S3 path variable <bucket name> to correspond to an S3 location within your local account:
    join_order_to_customer.write.mode("overwrite").format("parquet").option("path", "s3://<bucket name>/data/tina/order_and_product/").save()

The preceding query writes the created dataset as Parquet files in the S3 bucket specified.

Data scientist: Alex

Complete the following steps:

  1. Log in using the URL you located in the previous step.
  2. Enter Microsoft AD user [email protected] and your password.
  3. Choose the Amazon SageMaker Studio tile.
  4. In the SageMaker Studio UI, start a notebook:
    1. Choose File, New, and Notebook.
    2. For Image, choose SparkMagic.
    3. For Kernel, choose PySpark.
    4. For Instance Type, choose ml.t3.medium.
    5. Choose Select.
  5. When the notebook kernel starts, connect to the EMR cluster by running the following code:
    %load_ext sagemaker_studio_analytics_extension.magics
    %sm_analytics emr connect --cluster-id <EMR Cluster ID> --auth-type Kerberos --language python

  6. Enter Microsoft AD [email protected] and your password (note that [email protected] is case-sensitive).
  7. Choose Connect. Now we can test Alex’s data access.
  8. In a new cell, enter the following query and run the cell:
    %%sql
    show tables from staging

    Returned data will indicate the table objects accessible to Alex. Note that the customers table is missing.

  9. In a new cell, run the following:
    %%sql
    select * from staging.orders limit 5

Returned data will include columns Alex has been granted access.

Let’s test Alex’s access to customer data.

  1. In a new cell, run the following:
    %%sql
    select * from staging.customers limit 5

The preceding query will result in an Access Denied error because Alex doesn’t have access to customers.

We can verify Ranger is responsible for the denial by looking at the CloudWatch logs.

Now that you can successfully access data, feel free to interactively explore, visualize, prepare, and model the data using the different user personas.

Clean up

When you’re finished experimenting with this solution, clean up your resources:

  1. Shut down and update SageMaker Studio and Studio apps. Ensure that all apps created as part of this post are deleted before deleting the stack.
  2. Change the identity source for IAM Identity Center back to Identity Center Directory.
  3. Delete the directory AWSEMR.COM from Directory Services.
  4. Empty the S3 buckets created by the CloudFormation stacks.
  5. Delete the stacks via the AWS CloudFormation console for the non-nested stacks starting in reverse order.

Conclusion

This post showed how you can implement fine-grained access control in SageMaker Studio and Amazon EMR using Apache Ranger and Microsoft Active Directory. We also demonstrated how multiple SageMaker Studio users can connect to the same EMR cluster and access different tables and columns using Apache Ranger, wherein each user is scoped with permissions matching their individual level of access to data. In addition, we demonstrated how the individual users can access separate S3 folders for storing their intermediate data. We detailed the steps required to set up the integration and provided CloudFormation templates to set up the base infrastructure from end to end.

To learn more about using Amazon EMR with SageMaker Studio, refer to Prepare Data using Amazon EMR. We encourage you to try out this new functionality, and connect with the Machine Learning & AI community if you have any questions or feedback!

Appendix: Apache Ranger troubleshooting

The sync between Active Directory and Apache Ranger is set for every 24 hours. To force a sync, complete the following steps:

  1. Connect to the Apache Ranger server using SSH. This can be done using directly or Session Manager, a capability of AWS Systems Manager, or through AWS Cloud9.
  2. Once connected, issue the following commands:
    sudo /usr/bin/ranger-usersync stop || true
    sudo /usr/bin/ranger-usersync start
    sudo chkconfig ranger-usersync on

  3. To confirm the sync, open the Ranger console as an admin.
  4. Choose Audit in the top banner.
  5. Choose the User Sync tab and confirm the event time.

About the Authors

Rahul Sarda is a Senior Analytics & ML Specialist at AWS. He is a seasoned leader with over 20 years of experience, who is passionate about helping customers build scalable data and analytics solutions to gain timely insights and make critical business decisions. In his spare time, he enjoys spending time with his family, stay healthy, running and road cycling.

Varun Rao Bhamidimarri is a Sr Manager, AWS Analytics Specialist Solutions Architect team. His focus is helping customers with adoption of cloud-enabled analytics solutions to meet their business requirements. Outside of work, he loves spending time with his wife and two kids, stay healthy, mediate and recently picked up gardening during the lockdown.

Approaches for migrating users to Amazon Cognito user pools

Post Syndicated from Edward Sun original https://aws.amazon.com/blogs/security/approaches-for-migrating-users-to-amazon-cognito-user-pools/

Update: An earlier version of this post was published on September 14, 2017, on the Front-End Web and Mobile Blog.


Amazon Cognito user pools offer a fully managed OpenID Connect (OIDC) identity provider so you can quickly add authentication and control access to your mobile app or web application. User pools scale to millions of users and add layers of additional features for security, identity federation, app integration, and customization of the user experience. Amazon Cognito is available in regions around the globe, processing over 100 billion authentications each month. You can take advantage of security features when using user pools in Cognito, such as email and phone number verification, multi-factor authentication, and advanced security features, such as compromised credentials detection, and adaptive authentications.

Many customers ask about the best way to migrate their existing users to Amazon Cognito user pools. In this blog post, we describe several different recommended approaches and provide step-by-step instructions on how to implement them.

Key considerations

The main consideration when migrating users across identity providers is maintaining a consistent end-user experience. Ideally, users can continue to use their existing passwords so that their experience is seamless. However, security best practices dictate that passwords should never be stored directly as cleartext in a user store. Instead, passwords are used to compute cryptographic hashes and verifiers that can later be used to verify submitted passwords. This means that you cannot securely export passwords in cleartext form from an existing user store and import them into a Cognito user pool. You might ask your users to choose a new password during the migration. Or, if you want to retain the existing passwords, you need to retain access to the existing hashes and verifiers, at least during the migration period.

A secondary consideration is the migration timeline. For example, do you need a faster migration timeline because your current identity store’s license is expiring? Or do you prefer a slow and steady migration because you are modernizing your current application, and it takes time to connect your existing systems to the new identity provider?

The following two methods define our recommended approaches for migrating existing users into a user pool:

  • Bulk user import – Export your existing users into a comma-separated (.csv) file, and then upload this .csv file to import users into a user pool. Your desired user attributes (except passwords) can be included and mapped to attributes in the target user pool. This approach requires users to reset their passwords when they sign in with Cognito. You can choose to migrate your existing user store entirely in a single import job or split users into multiple jobs for parallel or incremental processing.
  • Just-in-time user migration – Migrate users just in time into a Cognito user pool as they sign in to your mobile or web app. This approach allows users to retain their current passwords, because the migration process captures and verifies the password during the sign-in process, seamlessly migrating them to the Cognito user pool.

In the following sections, we describe the bulk user import and just-in-time user migration methods in more detail and then walk through the steps of each approach.

Bulk user import

You perform bulk import of users into an Amazon Cognito user pool by uploading a .csv file that contains user profile data, including usernames, email addresses, phone numbers, and other attributes. You can download a template .csv file for your user pool from Cognito, with a user schema structured in the template header.

Following is an example of performing bulk user import.

To create an import job

  1. Open the Cognito user pool console and select the target user pool for migration.
  2. On the Users tab, navigate to the Import users section, and choose Create import job.
  3. Figure 1: Create import job

    Figure 1: Create import job

  4. In the Create import job dialog box, download the template.csv file for user import.
  5. Export your existing user data from your existing user directory or store your data into the .csv file
  6. Match the user attribute types with column headings in the template. Each user must have an email address or a phone number that is marked as verified in the .csv file, in order to receive the password reset confirmation code.
  7. Figure 2: Configure import job

    Figure 2: Configure import job

  8. Go back to the Create import job dialog box (as shown in Figure 2) and do the following:
    1. Enter a Job name.
    2. Choose to Create a new IAM role or Use an existing IAM role. This role grants Amazon Cognito permission to write to Amazon CloudWatch Logs in your account, so that Cognito can provide logs for successful imports and errors for skipped or failed transactions.
    3. Upload the .csv file that you have prepared, and choose Create and start job.

Depending on the size of the .csv file, the job can run for minutes or hours, and you can follow the status from that same page in the Amazon Cognito console.

Figure 3: Check import job status

Figure 3: Check import job status

Cognito runs through the import job and imports users with a RESET_REQUIRED state. When users attempt to sign in, Cognito will return PasswordResetRequiredException from the sign-in API, and the app should direct the user into the ForgotPassword flow.

Figure 4: View imported user

Figure 4: View imported user

The bulk import approach can also be used continuously to incrementally import users. You can set up an Extract-Transform-Load (ETL) batch job process to extract incremental changes to your existing user directories, such as the new sign-ups on the existing systems before you switch over to a Cognito user pool. Your batch job will transform the changes into a .csv file to map user attribute schemas, and load the .csv file as a Cognito import job through the CreateUserImportJob CLI or SDK operation. Then start the import job through the StartUserImportJob CLI or SDK operation. For more information, see Importing users into user pools in the Amazon Cognito Developer Guide.

Just-in-time user migration

The just-in-time (JIT) user migration method involves first attempting to sign in the user through the Amazon Cognito user pool. Then, if the user doesn’t exist in the Cognito user pool, Cognito calls your Migrate User Lambda trigger and sends the username and password to the Lambda trigger to sign the user in through the existing user store. If successful, the Migrate User Lambda trigger will also fetch user attributes and return them to Cognito. Then Cognito silently creates the user in the user pool with user attributes, as well as salts and password verifiers from the user-provided password. With the Migrate User Lambda trigger, your client app can start to use the Cognito user pool to sign in users who have already been migrated, and continue migrating users who are signing in for the first time towards the user pool. This just-in-time migration approach helps to create a seamless authentication experience for your users.

Cognito, by default, uses the USER_SRP_AUTH authentication flow with the Secure Remote Password (SRP) protocol. This flow doesn’t involve sending the password across the network, but rather allows the client to exchange a cryptographic proof with the Cognito service to prove the client’s knowledge of the password. For JIT user migration, Cognito needs to verify the username and password against the existing user store. Therefore, you need to enable a different Cognito authentication flow. You can choose to use either the USER_PASSWORD_AUTH flow for client-side authentication or the ADMIN_USER_PASSWORD_AUTH flow for server-side authentication. This will allow the password to be sent to Cognito over an encrypted TLS connection, and allow Cognito to pass the information to the Lambda function to perform user authentication against the original user store.

This JIT approach might not be compatible with existing identity providers that have multi-factor authentication (MFA) enabled, because the Lambda function cannot support multiple rounds of challenges. If the existing identity provider requires MFA, you might consider the alternative JIT migration approach discussed later in this blog post.

Figure 5 illustrates the steps for the JIT sign-in flow. The mobile or web app first tries to sign in the user in the user pool. If the user isn’t already in the user pool, Cognito handles user authentication and invokes the Migrate User Lambda trigger to migrate the user. This flow keeps the logic in the app simple and allows the app to use the Amazon Cognito SDK to sign in users in the standard way. The migration logic takes place in the Lambda function in the backend.

Figure 5: JIT migration user authentication flow

Figure 5: JIT migration user authentication flow

The flow in Figure 5 starts in the mobile or web app, which attempts to sign in the user by using the AWS SDK. If the user doesn’t exist in the user pool, the migration attempt starts. Cognito calls the Migrate User Lambda trigger with triggerSource set to UserMigration_Authentication, and passes the user’s username and password in the request in order to attempt to migrate the user.

This approach also works in the forgot password flow shown in Figure 6, where the user has forgotten their password and hasn’t been migrated yet. In this case, once the user makes a “Forgot Password” request, your mobile or web app will send a forgot password request to Cognito. Cognito invokes your Migrate User Lambda trigger with triggerSource set to UserMigration_ForgotPassword, and passes the username in the request in order to attempt user lookup, migrate the user profile, and facilitate the password reset process.

Figure 6: JIT migration forgot password flow

Figure 6: JIT migration forgot password flow

Just-in-time user migration sample code

In this section, we show sample source codes for a Migrate User Lambda trigger overall structure. We will fill in the commented sections with additional code, shown later in the section. When you set up your own Lambda function, configure a Lambda execution role to grant permissions for CloudWatch logs.

const handler = async (event) => {
    if (event.triggerSource == "UserMigration_Authentication") {
        //***********************************************************************
        // Attempt to sign in the user or verify the password with existing identity store
        // (shown in the Section A – Migrate User of this post)
        //***********************************************************************
    }
    else if (event.triggerSource == "UserMigration_ForgotPassword") {
       //***********************************************************************
       // Attempt to look up the user in your existing identity store
       // (shown in the section B – Forget Password of this post)
       //***********************************************************************
    }
    return event;
};
export { handler };

In the migration flow, the Lambda trigger will sign in the user and verify the user’s password in the existing user store. That may involve a sign-in attempt against your existing user store or a check of the password against a stored hash. You need to customize this step based on your existing setup. You can also create a function to fetch user attributes that you want to migrate. If your existing user store conforms to the OIDC specification, you can parse the ID Token claims to retrieve the user’s attributes. The following example shows how to set the username and attributes for the migrated user.

// Section A – Migrate User
if (event.triggerSource == "UserMigration_Authentication") {
// Attempt to sign in the user or verify the password with the existing user store.
// Add an authenticateUser() functionbased on your existing user store setup. 
    const user = await authenticateUser(event.userName, event.request.password);
    if (user) {
        // Migrating user attributes from the source user store. You can migrate additional attributes as needed.
        event.response.userAttributes = {
            // Setting username and email address
            username: event.userName,
            email: user.emailAddress,
            email_verified: "true",
        };
        // Setting user status to CONFIRMED to autoconfirm users so they can sign in to the user pool
        event.response.finalUserStatus = "CONFIRMED";
        // Setting messageAction to SUPPRESS to decline to send the welcome message that Cognito usually sends to new users
        event.response.messageAction = "SUPPRESS";
        }
    }

The user is now migrated from the existing user store to the user pool, as well as the user’s attributes. Users will also be redirected to your application with the authorization code or JSON Web Tokens, depending on the OAuth 2.0 grant types you configured in the user pool.

Let’s look at the forgot password flow. Your Lambda function calls the existing user store and migrates other attributes in the user’s profile first, and then Lambda sets user attributes in the response to the Cognito user pool. Cognito initiates the ForgotPassword flow and sends a confirmation code to the user to confirm the password reset process. The user needs to have a verified email address or phone number migrated from the existing user store to receive the forgot password confirmation code. The following sample code demonstrates how to complete the ForgotPassword flow.

// Section B – Forgot Password
else if (event.triggerSource == "UserMigration_ForgotPassword") {
        // Look up the user in your existing user store service.  
		// Add a lookupUser() function based on your existing user store setup. 
        const lookupResult = await lookupUser(event.userName);
        if (lookupResult) {
            // Setting user attributes from the source user store
            event.response.userAttributes = {
                username: event.userName,
                // Required to set verified communication to receive password recovery code
                email: lookupResult.emailAddress,
                email_verified: "true",
            };
            event.response.finalUserStatus = "RESET_REQUIRED";
            event.response.messageAction = "SUPPRESS";
        }
    }

Just-in-time user migration – alternative approach

Using the Migrate User Lambda trigger, we showed the JIT migration approach where the app switches to use the Cognito user pool at the beginning of the migration period, to interface with the user for signing in and migrating them from the existing user store. An alternative JIT approach is to maintain the existing systems and user store, but to silently create each user in the Cognito user pool in a backend process as users sign in, then switch over to use Cognito after enough users have been migrated.

Figure 7: JIT migration alternative approach with backend process

Figure 7: JIT migration alternative approach with backend process

Figure 7 shows this alternative approach in depth. When an end user signs in successfully in your mobile or web app, the backend migration process is initiated. This backend process first calls the Cognito admin API operation, AdminCreateUser, to create users and map user attributes in the destination user pool. The user will be created with a temporary password and be placed in FORCE_CHANGE_PASSWORD status. If you capture the user password during the sign-in process, you can also migrate the password by setting it permanently for the newly created user in the Cognito user pool using the AdminSetUserPassword API operation. This operation will also set the user status to CONFIRMED to allow the user to sign in to Cognito using the existing password.

Following is a code example for the AdminCreateUser function using the AWS SDK for JavaScript.

var params = {
    MessageAction: "SUPPRESS",
    UserAttributes: [{
        Name: "name",
        Value: "Nikki Wolf"
    },
    {
        Name: "email",
        Value: "[email protected]"
    },
    {
        Name: "email_verified",
        Value: "True"
    }
    ],
    UserPoolId: "us-east-1_EXAMPLE",
    Username: "nikki_wolf"
};
const cognito = new CognitoIdentityProviderClient();
const createUserCommand  = new AdminCreateUserCommand(params);
await cognito.send (createUserCommand);

The following is a code example for the AdminSetUserPassword function.

var params = {
    UserPoolId: 'us-east-1_EXAMPLE' ,
    Username: 'nikki_wolf' ,
    Password: 'ExamplePassword1$' ,
    Permanent: true
};
const cognito = new CognitoIdentityProviderClient();
const setUserPasswordCommand = new AdminSetUserPasswordCommand(params);
await cognito.send(setUserPasswordCommand);

This alternative approach does not require the app to update its authentication codebase until a majority of users are migrated, but you need to propagate user attribute changes and new user signups from the existing systems to Cognito. If you are capturing and migrating passwords, you should also build a similar logic to capture password changes in existing systems and set the new password in the user pool to keep it synchronized until you perform a full switchover from the existing identity store to the Cognito user pool.

Summary and best practices

In this post, we described our two recommended approaches for migrating users into an Amazon Cognito user pool. You can decide which approach is best suited for your use case. The bulk method is simpler to implement, but it doesn’t preserve user passwords like the just-in-time migration does. The just-in-time migration is transparent to users and mitigates the potential attrition of users that can occur when users need to reset their passwords.

You could also consider a hybrid approach, where you first apply JIT migration as users are actively signing in to your app, and perform bulk import for the remaining less-active users. This hybrid approach helps provide a good experience for your active user communities, while being able to decommission existing user stores in a manageable timeline because you don’t need to wait for every user to sign in and be migrated through JIT migration.

We hope you can use these explanations and code samples to set up the most suitable approach for your migration project.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Edward Sun

Edward Sun

Edward is a Security Specialist Solutions Architect focused on identity and access management. He loves helping customers throughout their cloud transformation journey with architecture design, security best practices, migration, and cost optimizations. Outside of work, Edward enjoys hiking, golfing, and cheering for his alma mater, the Georgia Bulldogs.

GoDaddy benchmarking results in up to 24% better price-performance for their Spark workloads with AWS Graviton2 on Amazon EMR Serverless

Post Syndicated from Mukul Sharma original https://aws.amazon.com/blogs/big-data/godaddy-benchmarking-results-in-up-to-24-better-price-performance-for-their-spark-workloads-with-aws-graviton2-on-amazon-emr-serverless/

This is a guest post co-written with Mukul Sharma, Software Development Engineer, and Ozcan IIikhan, Director of Engineering from GoDaddy.

GoDaddy empowers everyday entrepreneurs by providing all the help and tools to succeed online. With more than 22 million customers worldwide, GoDaddy is the place people come to name their ideas, build a professional website, attract customers, and manage their work.

GoDaddy is a data-driven company, and getting meaningful insights from data helps us drive business decisions to delight our customers. At GoDaddy, we embarked on a journey to uncover the efficiency promises of AWS Graviton2 on Amazon EMR Serverless as part of our long-term vision for cost-effective intelligent computing.

In this post, we share the methodology and results of our benchmarking exercise comparing the cost-effectiveness of EMR Serverless on the arm64 (Graviton2) architecture against the traditional x86_64 architecture. EMR Serverless on Graviton2 demonstrated an advantage in cost-effectiveness, resulting in significant savings in total run costs. We achieved 23.85% improvement in price-performance for sample production Spark workloads—an outcome that holds tremendous potential for businesses striving to maximize their computing efficiency.

Solution overview

GoDaddy’s intelligent compute platform envisions simplification of compute operations for all personas, without limiting power users, to ensure out-of-box cost and performance optimization for data and ML workloads. As a part of this vision, GoDaddy’s Data & ML Platform team plans to use EMR Serverless as one of the compute solutions under the hood.

The following diagram shows a high-level illustration of the intelligent compute platform vision.

Benchmarking EMR Serverless for GoDaddy

EMR Serverless is a serverless option in Amazon EMR that eliminates the complexities of configuring, managing, and scaling clusters when running big data frameworks like Apache Spark and Apache Hive. With EMR Serverless, businesses can enjoy numerous benefits, including cost-effectiveness, faster provisioning, simplified developer experience, and improved resilience to Availability Zone failures.

At GoDaddy, we embarked on a comprehensive study to benchmark EMR Serverless using real production workflows at GoDaddy. The purpose of the study was to evaluate the performance and efficiency of EMR Serverless and develop a well-informed adoption plan. The results of the study have been extremely promising, showcasing the potential of EMR Serverless for our workloads.

Having achieved compelling results in favor of EMR Serverless for our workloads, our attention turned to evaluating the utilization of the Graviton2 (arm64) architecture on EMR Serverless. In this post, we focus on comparing the performance of Graviton2 (arm64) with the x86_64 architecture on EMR Serverless. By conducting this apples-to-apples comparative analysis, we aim to gain valuable insights into the benefits and considerations of using Graviton2 for our big data workloads.

By using EMR Serverless and exploring the performance of Graviton2, GoDaddy aims to optimize their big data workflows and make informed decisions regarding the most suitable architecture for their specific needs. The combination of EMR Serverless and Graviton2 presents an exciting opportunity to enhance the data processing capabilities and drive efficiency in our operations.

AWS Graviton2

The Graviton2 processors are specifically designed by AWS, utilizing powerful 64-bit Arm Neoverse cores. This custom-built architecture provides a remarkable boost in price-performance for various cloud workloads.

In terms of cost, Graviton2 offers an appealing advantage. As indicated in the following table, the pricing for Graviton2 is 20% lower compared to the x86 architecture option.

   x86_64  arm64 (Graviton2) 
per vCPU per hour $0.052624 $0.042094
per GB per hour $0.0057785 $0.004628
per storage GB per hour* $0.000111

*Ephemeral storage: 20 GB of ephemeral storage is available for all workers by default—you pay only for any additional storage that you configure per worker.

For specific pricing details and current information, refer to Amazon EMR pricing.

AWS benchmark

The AWS team performed benchmark tests on Spark workloads with Graviton2 on EMR Serverless using the TPC-DS 3 TB scale performance benchmarks. The summary of their analysis are as follows:

  • Graviton2 on EMR Serverless demonstrated an average improvement of 10% for Spark workloads in terms of runtime. This indicates that the runtime for Spark-based tasks was reduced by approximately 10% when utilizing Graviton2.
  • Although the majority of queries showcased improved performance, a small subset of queries experienced a regression of up to 7% on Graviton2. These specific queries showed a slight decrease in performance compared to the x86 architecture option.
  • In addition to the performance analysis, the AWS team considered the cost factor. Graviton2 is offered at a 20% lower cost than the x86 architecture option. Taking this cost advantage into account, the AWS benchmark set yielded an overall 27% better price-performance for workloads. This means that by using Graviton2, users can achieve a 27% improvement in performance per unit of cost compared to the x86 architecture option.

These findings highlight the significant benefits of using Graviton2 on EMR Serverless for Spark workloads, with improved performance and cost-efficiency. It showcases the potential of Graviton2 in delivering enhanced price-performance ratios, making it an attractive choice for organizations seeking to optimize their big data workloads.

GoDaddy benchmark

During our initial experimentation, we observed that arm64 on EMR Serverless consistently outperformed or performed on par with x86_64. One of the jobs showed a 7.51% increase in resource usage on arm64 compared to x86_64, but due to the lower price of arm64, it still resulted in a 13.48% cost reduction. In another instance, we achieved an impressive 43.7% reduction in run cost, attributed to both the lower price and reduced resource utilization. Overall, our initial tests indicated that arm64 on EMR Serverless delivered superior price-performance compared to x86_64. These promising findings motivated us to conduct a more comprehensive and rigorous study.

Benchmark results

To gain a deeper understanding of the value of Graviton2 on EMR Serverless, we conducted our study using real-life production workloads from GoDaddy, which are scheduled to run at a daily cadence. Without any exceptions, EMR Serverless on arm64 (Graviton2) is significantly more cost-effective compared to the same jobs run on EMR Serverless on the x86_64 architecture. In fact, we recorded an impressive 23.85% improvement in price-performance across the sample GoDaddy jobs using Graviton2.

Like the AWS benchmarks, we observed slight regressions of less than 5% in the total runtime of some jobs. However, given that these jobs will be migrated from Amazon EMR on EC2 to EMR Serverless, the overall total runtime will still be shorter due to the minimal provisioning time in EMR Serverless. Additionally, across all jobs, we observed an average speed up of 2.1% in addition to the cost savings achieved.

These benchmarking results provide compelling evidence of the value and effectiveness of Graviton2 on EMR Serverless. The combination of improved price-performance, shorter runtimes, and overall cost savings makes Graviton2 a highly attractive option for optimizing big data workloads.

Benchmarking methodology

As an extension of a larger benchmarking EMR Serverless for GoDaddy study, where we divided Spark jobs into brackets based on total runtime (quick-run, medium-run, long-run), we measured effect of architecture (arm64 vs. x86_64) on total cost and total runtime. All other parameters were kept the same to achieve an apples-to-apples comparison.

The team followed these steps:

  1. Prepare the data and environment.
  2. Choose two random production jobs from each job bracket.
  3. Make necessary changes to avoid inference with actual production outputs.
  4. Run tests to execute scripts over multiple iterations to collect accurate and consistent data points.
  5. Validate input and output datasets, partitions, and row counts to ensure identical data processing.
  6. Gather relevant metrics from the tests.
  7. Analyze results to draw insights and conclusions.

The following table shows the summary of an example Spark job.

Metric  EMR Serverless (Average) – X86_64  EMR Serverless (Average) – Graviton  X86_64 vs Graviton (% Difference) 
Total Run Cost $2.76 $1.85 32.97%

Total Runtime

(hh:mm:ss)

00:41:31 00:34:32 16.82%
EMR Release Label emr-6.9.0
Job Type Spark
Spark Version Spark 3.3.0
Hadoop Distribution Amazon 3.3.3
Hive/HCatalog Version Hive 3.1.3, HCatalog 3.1.3

Summary of results

The following table presents a comparison of job performance between EMR Serverless on arm64 (Graviton2) and EMR Serverless on x86_64. For each architecture, every job was run at least three times to obtain the accurate average cost and runtime.

 Job  Average x86_64 Cost Average arm64 Cost Average x86_64 Runtime (hh:mm:ss) Average arm64 Runtime (hh:mm:ss)  Average Cost Savings %  Average Performance Gain % 
1 $1.64 $1.25 00:08:43 00:09:01 23.89% -3.24%
2 $10.00 $8.69 00:27:55 00:28:25 13.07% -1.79%
3 $29.66 $24.15 00:50:49 00:53:17 18.56% -4.85%
4 $34.42 $25.80 01:20:02 01:24:54 25.04% -6.08%
5 $2.76 $1.85 00:41:31 00:34:32 32.97% 16.82%
6 $34.07 $24.00 00:57:58 00:51:09 29.57% 11.76%
Average  23.85% 2.10%

Note that the improvement calculations are based on higher-precision results for more accuracy.

Conclusion

Based on this study, GoDaddy observed a significant 23.85% improvement in price-performance for sample production Spark jobs utilizing the arm64 architecture compared to the x86_64 architecture. These compelling results have led us to strongly recommend internal teams to use arm64 (Graviton2) on EMR Serverless, except in cases where there are compatibility issues with third-party packages and libraries. By adopting an arm64 architecture, organizations can achieve enhanced cost-effectiveness and performance for their workloads, contributing to more efficient data processing and analytics.


About the Authors

Mukul Sharma is a Software Development Engineer on Data & Analytics (DnA) organization at GoDaddy. He is a polyglot programmer with experience in a wide array of technologies to rapidly deliver scalable solutions. He enjoys singing karaoke, playing various board games, and working on personal programming projects in his spare time.

Ozcan Ilikhan is a Director of Engineering on Data & Analytics (DnA) organization at GoDaddy. He is passionate about solving customer problems and increasing efficiency using data and ML/AI. In his spare time, he loves reading, hiking, gardening, and working on DIY projects.

Harsh Vardhan Singh Gaur is an AWS Solutions Architect, specializing in analytics. He has over 6 years of experience working in the field of big data and data science. He is passionate about helping customers adopt best practices and discover insights from their data.

Ramesh Kumar Venkatraman is a Senior Solutions Architect at AWS who is passionate about containers and databases. He works with AWS customers to design, deploy, and manage their AWS workloads and architectures. In his spare time, he loves to play with his two kids and follows cricket.

Aggregating, searching, and visualizing log data from distributed sources with Amazon Athena and Amazon QuickSight

Post Syndicated from Pratima Singh original https://aws.amazon.com/blogs/security/aggregating-searching-and-visualizing-log-data-from-distributed-sources-with-amazon-athena-and-amazon-quicksight/

Customers using Amazon Web Services (AWS) can use a range of native and third-party tools to build workloads based on their specific use cases. Logs and metrics are foundational components in building effective insights into the health of your IT environment. In a distributed and agile AWS environment, customers need a centralized and holistic solution to visualize the health and security posture of their infrastructure.

You can effectively categorize the members of the teams involved using the following roles:

  1. Executive stakeholder: Owns and operates with their support staff and has total financial and risk accountability.
  2. Data custodian: Aggregates related data sources while managing cost, access, and compliance.
  3. Operator or analyst: Uses security tooling to monitor, assess, and respond to related events such as service disruptions.

In this blog post, we focus on the data custodian role. We show you how you can visualize metrics and logs centrally with Amazon QuickSight irrespective of the service or tool generating them. We use Amazon Simple Storage Service (Amazon S3) for storage, AWS Glue for cataloguing, and Amazon Athena for querying the data and creating structured query language (SQL) views for QuickSight to consume.

Target architecture

This post guides you towards building a target architecture in line with the AWS Well-Architected Framework. The tiered and multi-account target architecture, shown in Figure 1, uses account-level isolation to separate responsibilities across the various roles identified above and makes access management more defined and specific to those roles. The workload accounts generate the telemetry around the applications and infrastructure. The data custodian account is where the data lake is deployed and collects the telemetry. The operator account is where the queries and visualizations are created.

Throughout the post, I mention AWS services that reduce the operational overhead in one or more stages of the architecture.

Figure 1: Data visualization architecture

Figure 1: Data visualization architecture

Ingestion

Irrespective of the technology choices, applications and infrastructure configurations should generate metrics and logs that report on resource health and security. The format of the logs depends on which tool and which part of the stack is generating the logs. For example, the format of log data generated by application code can capture bespoke and additional metadata deemed useful from a workload perspective as compared to access logs generated by proxies or load balancers. For more information on types of logs and effective logging strategies, see Logging strategies for security incident response.

Amazon S3 is a scalable, highly available, durable, and secure object storage that you will use as the storage layer. To build a solution that captures events agnostic of the source, you must forward data as a stream to the S3 bucket. Based on the architecture, there are multiple tools you can use to capture and stream data into S3 buckets. Some tools support integration with S3 and directly stream data to S3. Resources like servers and virtual machines need forwarding agents such as Amazon Kinesis Agent, Amazon CloudWatch agent, or Fluent Bit.

Amazon Kinesis Data Streams provides a scalable data streaming environment. Using on-demand capacity mode eliminates the need for capacity provisioning and capacity management for streaming workloads. For log data and metric collection, you should use on-demand capacity mode, because log data generation can be unpredictable depending on the requests that are being handled by the environment. Amazon Kinesis Data Firehose can convert the format of your input data from JSON to Apache Parquet before storing the data in Amazon S3. Parquet is naturally compressed, and using Parquet native partitioning and compression allows for faster queries compared to JSON formatted objects.

Scalable data lake

Use AWS Lake Formation to build, secure, and manage the data lake to store log and metric data in S3 buckets. We recommend using tag-based access control and named resources to share the data in your data store to share data across accounts to build visualizations. Data custodians should configure access for relevant datasets to the operators who can use Athena to perform complex queries and build compelling data visualizations with QuickSight, as shown in Figure 2. For cross-account permissions, see Use Amazon Athena and Amazon QuickSight in a cross-account environment. You can also use Amazon DataZone to build additional governance and share data at scale within your organization. Note that the data lake is different to and separate from the Log Archive bucket and account described in Organizing Your AWS Environment Using Multiple Accounts.

Figure 2: Account structure

Figure 2: Account structure

Amazon Security Lake

Amazon Security Lake is a fully managed security data lake service. You can use Security Lake to automatically centralize security data from AWS environments, SaaS providers, on-premises, and third-party sources into a purpose-built data lake that’s stored in your AWS account. Using Security Lake reduces the operational effort involved in building a scalable data lake, as the service automates the configuration and orchestration for the data lake with Lake Formation. Security Lake automatically transforms logs into a standard schema—the Open Cybersecurity Schema Framework (OCSF) — and parses them into a standard directory structure, which allows for faster queries. For more information, see How to visualize Amazon Security Lake findings with Amazon QuickSight.

Querying and visualization

Figure 3: Data sharing overview

Figure 3: Data sharing overview

After you’ve configured cross-account permissions, you can use Athena as the data source to create a dataset in QuickSight, as shown in Figure 3. You start by signing up for a QuickSight subscription. There are multiple ways to sign in to QuickSight; this post uses AWS Identity and Access Management (IAM) for access. To use QuickSight with Athena and Lake Formation, you first must authorize connections through Lake Formation. After permissions are in place, you can add datasets. You should verify that you’re using QuickSight in the same AWS Region as the Region where Lake Formation is sharing the data. You can do this by checking the Region in the QuickSight URL.

You can start with basic queries and visualizations as described in Query logs in S3 with Athena and Create a QuickSight visualization. Depending on the nature and origin of the logs and metrics that you want to query, you can use the examples published in Running SQL queries using Amazon Athena. To build custom analytics, you can create views with Athena. Views in Athena are logical tables that you can use to query a subset of data. Views help you to hide complexity and minimize maintenance when querying large tables. Use views as a source for new datasets to build specific health analytics and dashboards.

You can also use Amazon QuickSight Q to get started on your analytics journey. Powered by machine learning, Q uses natural language processing to provide insights into the datasets. After the dataset is configured, you can use Q to give you suggestions for questions to ask about the data. Q understands business language and generates results based on relevant phrases detected in the questions. For more information, see Working with Amazon QuickSight Q topics.

Conclusion

Logs and metrics offer insights into the health of your applications and infrastructure. It’s essential to build visibility into the health of your IT environment so that you can understand what good health looks like and identify outliers in your data. These outliers can be used to identify thresholds and feed into your incident response workflow to help identify security issues. This post helps you build out a scalable centralized visualization environment irrespective of the source of log and metric data.

This post is part 1 of a series that helps you dive deeper into the security analytics use case. In part 2, How to visualize Amazon Security Lake findings with Amazon QuickSight, you will learn how you can use Security Lake to reduce the operational overhead involved in building a scalable data lake and centralizing log data from SaaS providers, on-premises, AWS, and third-party sources into a purpose-built data lake. You will also learn how you can integrate Athena with Security Lake and create visualizations with QuickSight of the data and events captured by Security Lake.

Part 3, How to share security telemetry per Organizational Unit using Amazon Security Lake and AWS Lake Formation, dives deeper into how you can query security posture using AWS Security Hub findings integrated with Security Lake. You will also use the capabilities of Athena and QuickSight to visualize security posture in a distributed environment.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Pratima Singh

Pratima Singh

Pratima is a Security Specialist Solutions Architect with Amazon Web Services based out of Sydney, Australia. She is a security enthusiast who enjoys helping customers find innovative solutions to complex business challenges. Outside of work, Pratima enjoys going on long drives and spending time with her family at the beach.

Security considerations for running containers on Amazon ECS

Post Syndicated from Mutaz Hajeer original https://aws.amazon.com/blogs/security/security-considerations-for-running-containers-on-amazon-ecs/

If you’re looking to enhance the security of your containers on Amazon Elastic Container Service (Amazon ECS), you can begin with the six tips that we’ll cover in this blog post. These curated best practices are recommended by Amazon Web Services (AWS) container and security subject matter experts in order to help raise your container security posture.

Before we jump into best practices, let’s look at the how the shared responsibility model works for Amazon ECS hosted on Amazon Elastic Compute Cloud (Amazon EC2) infrastructure compared to AWS Fargate. The security and compliance of a managed service like Amazon ECS is a shared responsibility between you and AWS. Generally speaking, AWS is responsible for security of the cloud whereas you, the customer, are responsible for security in the cloud. AWS is responsible for the management of the Amazon ECS control plane, including the infrastructure that’s needed to deliver a secure and reliable service. In this post, we’re going to focus on the areas of ECS security that you will be responsible for and provide guidance on what you need to do to adhere to these ECS security best practices.

Figure 1 shows the shared responsibility model for Amazon ECS hosted on an EC2 instance, in which the customer has more security responsibility to cover than when using ECS on Fargate. For example, the ECS agent and the worker node configuration is the customer’s responsibility to govern, because the customer is managing the EC2 instance. Therefore, the customer will have to manage the ECS agent and worker node as part of their configuration and management operations.

Figure 1: Responsibility model for Amazon ECS hosted on an Amazon EC2 instance

Figure 1: Responsibility model for Amazon ECS hosted on an Amazon EC2 instance

AWS assumes greater responsibility for infrastructure security for Fargate, as shown in Figure 2.

Figure 2: Responsibility model for Amazon ECS hosted on Fargate

Figure 2: Responsibility model for Amazon ECS hosted on Fargate

In Fargate, each task runs in its own virtual machine (VM). No two tasks share the operating system or kernel resources. With Fargate, AWS manages the security of the underlying instance in the cloud and the runtime that’s used to run your tasks. It also automatically scales your infrastructure on your behalf, which is something you should take into consideration if you’re starting your container journey and deciding on your infrastructure options.

With that, let’s go through these six Amazon ECS security best practices.

1 – Manage ECS access with IAM policies and roles

AWS Identity and Access Management (IAM) policies can help you control access to Amazon ECS. For this we recommend that you do the following:

  • Enforce least privilege when setting up policies for Amazon ECS resources – Use resource-level permissions to specify upon which resources you want to allow particular actions. For example, only allow a specific IAM user to stop a task that uses a specific task definition family on a specific ECS cluster.
  • Specify your task’s role – Make sure to define the right task role in your ECS task definition. The task role is used by your application in the task to make API calls to AWS services like Amazon Simple Storage Service (Amazon S3). This allows you to run your tasks by using an IAM role that has only the necessary permissions, without complete access to all services and resources within your account.
  • Create automated pipelines – Use Amazon CodePipeline or one of your other preferred continuous integration and continuous delivery (CI/CD) solutions to create pipelines that package and deploy your applications into ECS clusters. This way, you limit the users’ actions and delegate them to the automated pipeline. For an example of how to create pipelines, see Automatically build CI/CD pipelines and Amazon ECS clusters for microservices using AWS CDK.
  • Audit Amazon ECS API access – Track and monitor your AWS CloudTrail logs to identify who has access to your Amazon ECS APIs and whether that access is still warranted. You can then delete the IAM users, roles, and groups that aren’t in use and review the policies that are in place. For more information, see the AWS security audit guidelines.

2 – Secure your ECS network

Network security is an important item to work on as part of applying best practices to secure your Amazon ECS environment. This area includes several sub-areas such as firewalling, traffic routing, and network observability. Here’s what we recommend:

  • Network segmentation and isolation – Amazon ECS tasks are configured to operate in different network modes. AWS recommends the use of awsvpc as the preferred network mode. This is because it’s the only mode that you can use to assign security groups to tasks. After you configure your task to use this mode, the ECS agent automatically provisions and attaches an elastic network interface (ENI) to the task. When the ENI is provisioned, the task is enrolled in an AWS security group. The security group acts as a virtual firewall that you can use to control inbound and outbound traffic. It’s also the only mode that’s available for Fargate tasks on ECS if you choose to go that route.
  • Use network encryption where applicable – Encrypting network traffic helps prevent unauthorized users from intercepting and reading data when that data is transmitted across a network. With Amazon ECS, you can implement network encryption in different ways, such as with a service mesh (TLS), using AWS Nitro system instances, using server name indication (SNI) with an application load balancer, or end-to-end encryption with TLS certificates. If your service is fronted by a public-facing load balancer, use TLS/SSL to encrypt the traffic from the client’s browser to the load balancer and re-encrypt traffic to the backend if warranted. For more information, see Amazon ECS encryption in transit.
  • Create clusters in separate VPCs when network traffic needs to be strictly isolated – You should create clusters in separate virtual private clouds (VPCs) when network traffic needs to be strictly isolated. Avoid running workloads that have strict security requirements on clusters with workloads that don’t have to adhere to those requirements. When strict network isolation is mandatory, create clusters in separate VPCs and selectively expose services to other VPCs by using VPC endpoints. For more information, see VPC endpoints.
  • Configure AWS PrivateLink endpoints when possible – AWS PrivateLink is a networking technology that allows you to create private endpoints for different AWS services, including Amazon ECS. You should configure AWS PrivateLink endpoints when possible. If your security policy prevents you from attaching an internet gateway to your Amazon VPCs, then configure PrivateLink endpoints for ECS and other services such as Amazon Elastic Container Registry (Amazon ECR), AWS Secrets Manager, and Amazon CloudWatch. For more details, see the Amazon ECS Best Practices Guide.

3 – ECS secrets management

Secrets, such as API keys and database credentials, are frequently used by applications to gain access to other systems. They often consist of a username and password, a certificate, or an API key. Access to these secrets should be restricted to specific IAM principals that are using IAM and injected into containers at runtime. Here’s what we recommend:

  • Use Secrets Manager or Amazon EC2 Systems Manager Parameter Store for storing secret materials – Securely storing API keys, database credentials, and other secret materials is crucial to help prevent accidental exposure and unauthorized access. AWS recommends that you store these secrets in Secrets Manager or as an encrypted parameter in Amazon EC2 Systems Manager Parameter Store. These services are similar because they’re both managed key-value stores that use AWS Key Management Service (AWS KMS) to encrypt sensitive data. Secrets Manager, however, also includes the ability to automatically rotate secrets, generate random secrets, and share secrets across AWS accounts. Additionally, Amazon ECS does not support versioned parameters in Parameter Store. If you need to implement any of these features, use Secrets Manager; otherwise, use encrypted parameters. Also, you can use tools like Chamber to manage secrets. For more information, see this Knowledge Center article.
  • Mount the secret to a volume by using a sidecar container – Considering the elevated risk of data leakage with environmental variables, it’s recommended that you run a sidecar container that reads your secrets from Secrets Manager and writes them to a shared volume. This container can run and exit before the application container by using Amazon ECS container ordering. When you do this, the application container subsequently mounts the volume where the secret was written. This will help isolate secret management concerns and facilitates dynamic secret handling. For example, your application should be written to read the secret from the shared volume. Then, because the volume is scoped to the task, the volume is automatically deleted after the task stops. For more details about sidecar containers, see the aws-secret-sidecar-injector project in GitHub.

4 – Secure the ECS task and runtime

You should consider the container image as your first line of defense. An insecure, poorly constructed image can allow users to escape the bounds of the container and gain access to the host. You should do the following to mitigate the chances of this happening:

  • Secure your container’s images – Escape to host is a well-known container threat technique where bad actors use unsecured container images to escape the bounds of a container and gain access to the underlying host. We recommend that you scan your container’s images before deployment. For images stored on Amazon ECR, you can use Amazon Inspector to scan your images, along with Amazon EventBridge to be notified to take actions to either delete or rebuild insecure images. This process is shown in the architecture in Figure 3. You can find more details on how to create custom responses to Amazon Inspector findings with Amazon EventBridge in the Amazon Inspector User Guide.

    Figure 3: Sample architecture showing how to get notified of Amazon Inspector findings on a container’s image

    Figure 3: Sample architecture showing how to get notified of Amazon Inspector findings on a container’s image

  • Enable the ECR tag immutability feature – Threat actors could also try to push a compromised version of a container image into your Amazon ECR repository with an identical tag. A solution for this is to force a new tag for each new version of your image. You can do this by enabling the image tag mutability feature for your ECR repositories. You can find the Tag immutability setting on the Create repository page in the Amazon ECR console, under General settings, as shown in Figure 4.
    Figure 4: Enabling the tag immutability feature for your Amazon ECR repository

    Figure 4: Enabling the tag immutability feature for your Amazon ECR repository

  • Secure your containers and tasks
    • Define the USER parameter to use inside your container – Containers run by default as the root user, which doesn’t adhere to the principle of least privilege and can be misused. One recommendation is to make sure to run your containers as a non-root user by specifying the USER directive in your Dockerfile. You can enforce this when using a CI/CD pipeline by configuring the pipeline to fail the build if the USER directive is missing.
    • Don’t run your containers in privileged mode – Make sure to not run your containers in privileged mode, which can be a potential gap that allows unauthorized users to run commands within a container. You can use AWS Security Hub to detect containers that are running in privileged mode. Alternatively, you can use AWS Lambda to scan your task definitions for the use of the privileged parameter. Security Hub has a built-in control (ECS.4) to check whether the privileged parameter in the container definition of Amazon ECS task definitions is set to true.
  • Disable ECS Exec – Customers should disable the ECS Execute condition key for production environments. Disabling the key provides access control that can help prevent SSH access into running containers. You can do this by disabling the ECS:Enable-Execute-Command condition key.
  • Secure runtime – For Linux containers, make sure to add or drop Linux kernel capabilities in the task definition. You can do this either by using linuxParameters and applying SELinux labels or by using the AppArmor profile, which is a Linux security module that restricts a container’s capabilities, such as accessing parts of the file system. When you’re using the Fargate launch type, each Fargate task has its own isolation boundary and does not share the underlying kernel, CPU resources, memory resources, or elastic network interface with another task.

5 – ECS logging and monitoring

Logging and monitoring your container’s activity can help you quickly identify and investigate security incidents in your AWS environments. For example, threat actors might have escalated permissions and have access to your root user. Here’s what we recommend:

  • Monitor your root-user activities – Configure an Amazon EventBridge rule that detects root-user activities based on Amazon CloudTrail logs. For more details, see this blog post.
  • Monitor changes to your tasks and containers – Put appropriate events rules in place in Amazon EventBridge for the creation of and changes to your tasks and containers.
  • Monitor Amazon ECS scheduled tasks – If threat actors have enough privileges, they can abuse the ECS task scheduling feature to deploy containers that would run malicious code. Monitor this type of activity by using Amazon CloudTrail logs and get notifications. For more information about scheduling ECS tasks, see the Amazon ECS Developer Guide.
  • Monitor your container’s activity metrics – Another recommendation is to enable logging for your container and use Amazon CloudWatch to track activity metrics on your containers, such as CPU and memory utilization. This can help you detect if your resources are accessed and being used for malicious activities, such as launching DoS attacks. See Amazon ECS CloudWatch Container Insights for more information.
  • Use Amazon VPC Flow Logs to analyze the traffic to and from long-running tasks – You should use Amazon VPC Flow Logs to analyze the traffic to and from long-running tasks. Tasks that use awsvpc network mode get their own ENI. By setting tasks to use this mode, you can use VPC flow logs to monitor traffic that goes to and from individual tasks. A recent update to Amazon VPC Flow Logs (v3) enriches the logs with traffic metadata, including the VPC ID, subnet ID, and the instance ID. You can use this metadata to help narrow an investigation. For more information, see Amazon VPC Flow Logs. AWS cloud-native tools like Amazon GuardDuty inspect VPC flow logs and generate alerts and findings if unusual activity is detected.

6 – ECS security compliance

When using Amazon ECS, your compliance responsibility is determined by the sensitivity of your data, the compliance objectives of your company, and applicable laws and regulations. For example, with regards to the Payment Card Industry Data Security Standard (PCI-DSS), it’s important that you understand the complete flow of cardholder data (CHD) within your environment.

The temporary nature of containerized applications provides additional complexities when auditing configurations. As a result, customers need to maintain an awareness of all container configuration parameters, to make sure that compliance requirements are addressed throughout the phases of a container lifecycle. For additional information on adhering to PCI DSS compliance on Amazon ECS, see the Architecting on Amazon ECS for PCI DSS Compliance whitepaper.

One service that can help with monitoring Amazon ECS compliance is AWS Security Hub. You can use this service to monitor your usage of ECS as it relates to security best practices. Security Hub uses controls to evaluate resource configurations and security standards to help you comply with various compliance frameworks. For more information about using Security Hub to evaluate ECS resources, see Amazon ECS controls in the AWS Security Hub User Guide.

Conclusion

In this blog post, we presented a curated list of best practices for securing your Amazon ECS implementation. You can use these best practices as a starting point to increase the security posture of your ECS environment. You can always add, remove, or prioritize the best practice items based on your business needs and requirements. If you’re looking for more detailed guidance on securing ECS in your environment, we suggest that you take a look at Amazon ECS Security Best Practices.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on AWS re:Post or contact AWS Support.

Mutaz Hajeer

Mutaz Hajeer

Mutaz is a Senior Security Solutions Architect on the AWS Worldwide Commercial Sector Security Specialist team, working with customers in North America. Mutaz has been working within the cybersecurity field for 14 years and now focuses on threat detection and incident response services within AWS. Outside of work, he likes to coach, play, and watch soccer, along with spending time with his wife and three kids.

Ibtissam Liedri author

Ibtissam Liedri

Ibtissam is a Solutions Architect for AWS Financial Services. She assists financial services customers throughout their cloud journeys, helping them craft scalable, flexible, and resilient architectures. Ibtissam has an interest in cloud security with a focus on threat detection and incident response services within AWS and enjoys helping customers understand how to better build and secure their workloads.

Temi Adebambo

Temi Adebambo

Temi is the head of Security Solutions Architecture at AWS, with extensive experience leading technical teams and delivering enterprise-wide technology transformation programs. He has assisted Fortune 500 corporations with cloud security architecture, cyber risk management, compliance, IT security strategy, and governance. Prior to AWS, Temi served in various roles at Deloitte and PwC, providing consulting services in cybersecurity across industries.

Evolving cyber threats demand new security approaches – The benefits of a unified and global IT/OT SOC

Post Syndicated from Stuart Gregg original https://aws.amazon.com/blogs/security/evolving-cyber-threats-demand-new-security-approaches-the-benefits-of-a-unified-and-global-it-ot-soc/

In this blog post, we discuss some of the benefits and considerations organizations should think through when looking at a unified and global information technology and operational technology (IT/OT) security operations center (SOC). Although this post focuses on the IT/OT convergence within the SOC, you can use the concepts and ideas discussed here when thinking about other environments such as hybrid and multi-cloud, Industrial Internet of Things (IIoT), and so on.

The scope of assets has vastly expanded as organizations transition to remote work, and from increased interconnectivity through the Internet of Things (IoT) and edge devices coming online from around the globe, such as cyber physical systems. For many organizations, the IT and OT SOCs were separate, but there is a strong argument for convergence, which provides better context for the business outcomes of being able to respond to unexpected activity. In the ten security golden rules for IIoT solutions, AWS recommends deploying security audit and monitoring mechanisms across OT and IIoT environments, collecting security logs, and analyzing them using security information and event management (SIEM) tools within a SOC. SOCs are used to monitor, detect, and respond; this has traditionally been done separately for each environment. In this blog post, we explore the benefits and potential trade-offs of the convergence of these environments for the SOC. Although organizations should carefully consider the points raised throughout this blog post, the benefits of a unified SOC outweigh the potential trade-offs—visibility into the full threat chain propagating from one environment to another is critical for organizations as daily operations become more connected across IT and OT.

Traditional IT SOC

Traditionally, the SOC was responsible for security monitoring, analysis, and incident management of the entire IT environment within an organization—whether on-premises or in a hybrid architecture. This traditional approach has worked well for many years and ensures the SOC has the visibility to effectively protect the IT environment from evolving threats.

Note: Organizations should be aware of the considerations for security operations in the cloud which are discussed in this blog post.

Traditional OT SOC

Traditionally, OT, IT, and cloud teams have worked on separate sides of the air gap as described in the Purdue model. This can result in siloed OT, IIoT, and cloud security monitoring solutions, creating potential gaps in coverage or missing context that could otherwise have improved the response capability. To realize the full benefits of IT/OT convergence, IIoT, IT and OT must collaborate effectively to provide a broad perspective and the most effective defense. The convergence trend applies to newly connected devices and to how security and operations work together.

As organizations explore how industrial digital transformation can give them a competitive advantage, they’re using IoT, cloud computing, artificial intelligence and machine learning (AI/ML), and other digital technologies. This increases the potential threat surface that organizations must protect and requires a broad, integrated, and automated defense-in-depth security approach delivered through a unified and global SOC.
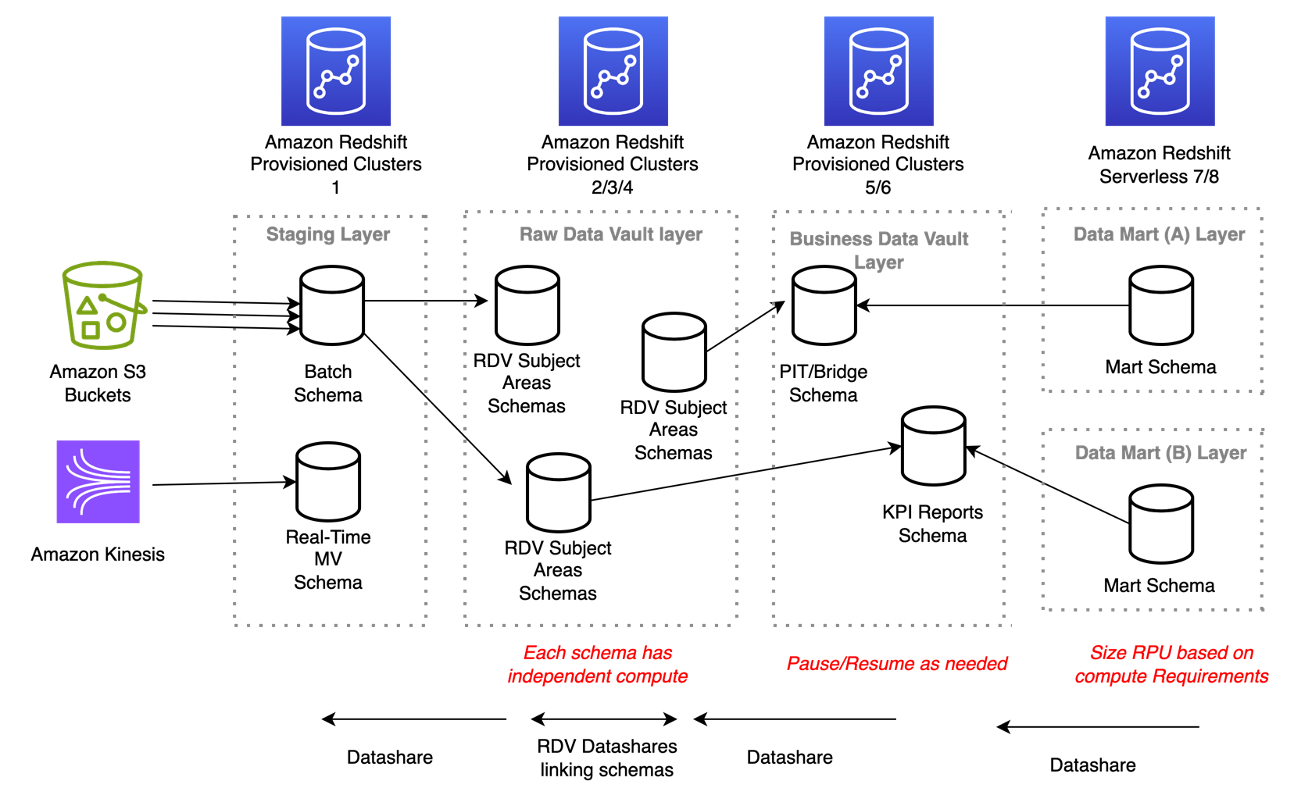
Without full visibility and control of traffic entering and exiting OT networks, the operations function might not be able to get full context or information that can be used to identify unexpected events. If a control system or connected assets such as programmable logic controllers (PLCs), operator workstations, or safety systems are compromised, threat actors could damage critical infrastructure and services or compromise data in IT systems. Even in cases where the OT system isn’t directly impacted, the secondary impacts can result in OT networks being shut down due to safety concerns over the ability to operate and monitor OT networks.

The SOC helps improve security and compliance by consolidating key security personnel and event data in a centralized location. Building a SOC is significant because it requires a substantial upfront and ongoing investment in people, processes, and technology. However, the value of an improved security posture is of great consideration compared to the costs.

In many OT organizations, operators and engineering teams may not be used to focusing on security; in some cases, organizations set up an OT SOC that’s independent from their IT SOC. Many of the capabilities, strategies, and technologies developed for enterprise and IT SOCs apply directly to the OT environment, such as security operations (SecOps) and standard operating procedures (SOPs). While there are clearly OT-specific considerations, the SOC model is a good starting point for a converged IT/OT cybersecurity approach. In addition, technologies such as a SIEM can help OT organizations monitor their environment with less effort and time to deliver maximum return on investment. For example, by bringing IT and OT security data into a SIEM, IT and OT stakeholders share access to the information needed to complete security work.

Benefits of a unified SOC

A unified SOC offers numerous benefits for organizations. It provides broad visibility across the entire IT and OT environments, enabling coordinated threat detection, faster incident response, and immediate sharing of indicators of compromise (IoCs) between environments. This allows for better understanding of threat paths and origins.

Consolidating data from IT and OT environments in a unified SOC can bring economies of scale with opportunities for discounted data ingestion and retention. Furthermore, managing a unified SOC can reduce overhead by centralizing data retention requirements, access models, and technical capabilities such as automation and machine learning.

Operational key performance indicators (KPIs) developed within one environment can be used to enhance another, promoting operational efficiency such as reducing mean time to detect security events (MTTD). A unified SOC enables integrated and unified security, operations, and performance, which supports comprehensive protection and visibility across technologies, locations, and deployments. Sharing lessons learned between IT and OT environments improves overall operational efficiency and security posture. A unified SOC also helps organizations adhere to regulatory requirements in a single place, streamlining compliance efforts and operational oversight.

By using a security data lake and advanced technologies like AI/ML, organizations can build resilient business operations, enhancing their detection and response to security threats.

Creating cross-functional teams of IT and OT subject matter experts (SMEs) help bridge the cultural divide and foster collaboration, enabling the development of a unified security strategy. Implementing an integrated and unified SOC can improve the maturity of industrial control systems (ICS) for IT and OT cybersecurity programs, bridging the gap between the domains and enhancing overall security capabilities.
Considerations for a unified SOC

There are several important aspects of a unified SOC for organizations to consider.

First, the separation of duty is crucial in a unified SOC environment. It’s essential to verify that specific duties are assigned to individuals based on their expertise and job function, allowing the most appropriate specialists to work on security events for their respective environments. Additionally, the sensitivity of data must be carefully managed. Robust access and permissions management is necessary to restrict access to specific types of data, maintaining that only authorized analysts can access and handle sensitive information. You should implement a clear AWS Identity and Access Management (IAM) strategy following security best practices across your organization to verify that the separation of duties is enforced.

Another critical consideration is the potential disruption to operations during the unification of IT and OT environments. To promote a smooth transition, careful planning is required to minimize any loss of data, visibility, or disruptions to standard operations. It’s crucial to recognize the differences in IT and OT security. The unique nature of OT environments and their close ties to physical infrastructure require tailored cybersecurity strategies and tools that address the distinct missions, challenges, and threats faced by industrial organizations. A copy-and-paste approach from IT cybersecurity programs will not suffice.

Furthermore, the level of cybersecurity maturity often varies between IT and OT domains. Investment in cybersecurity measures might differ, resulting in OT cybersecurity being relatively less mature compared to IT cybersecurity. This discrepancy should be considered when designing and implementing a unified SOC. Baselining the technology stack from each environment, defining clear goals and carefully architecting the solution can help ensure this discrepancy has been accounted for. After the solution has moved into the proof-of-concept (PoC) phase, you can start to testing for readiness to move the convergence to production.

You also must address the cultural divide between IT and OT teams. Lack of alignment between an organization’s cybersecurity policies and procedures with ICS and OT security objectives can impact the ability to secure both environments effectively. Bridging this divide through collaboration and clear communication is essential. This has been discussed in more detail in the post on managing organizational transformation for successful IT/OT convergence.

Unified IT/OT SOC deployment:

Figure 1 shows the deployment that would be expected in a unified IT/OT SOC. This is a high-level view of a unified SOC. In part 2 of this post, we will provide prescriptive guidance on how to design and build a unified and global SOC on AWS using AWS services and AWS Partner Network (APN) solutions.

Figure 1: Unified IT/OT SOC architecture

Figure 1: Unified IT/OT SOC architecture

The parts of the IT/OT unified SOC are the following:

Environment: There are multiple environments, including a traditional IT on-premises organization, OT environment, cloud environment, and so on. Each environment represents a collection of security events and log sources from assets.

Data lake: A centralized place for data collection, normalization, and enrichment to verify that raw data from the different environments is standardized into a common scheme. The data lake should support data retention and archiving for long term storage.

Visualize: The SOC includes multiple dashboards based on organizational and operational needs. Dashboards can cover scenarios for multiple environments including data flows between IT and OT environments. There are also specific dashboards for the individual environments to cover each stakeholder’s needs. Data should be indexed in a way that allows humans and machines to query the data to monitor for security and performance issues.

Security analytics: Security analytics are used to aggregate and analyze security signals and generate higher fidelity alerts and to contextualize OT signals against concurrent IT signals and against threat intelligence from reputable sources.
Detect, alert, and respond: Alerts can be set up for events of interest based on data across both individual and multiple environments. Machine learning should be used to help identify threat paths and events of interest across the data.

Conclusion

Throughout this blog post, we’ve talked through the convergence of IT and OT environments from the perspective of optimizing your security operations. We looked at the benefits and considerations of designing and implementing a unified SOC.

Visibility into the full threat chain propagating from one environment to another is critical for organizations as daily operations become more connected across IT and OT. A unified SOC is the nerve center for incident detection and response and can be one of the most critical components in improving your organization’s security posture and cyber resilience.

If unification is your organization’s goal, you must fully consider what this means and design a plan for what a unified SOC will look like in practice. Running a small proof of concept and migrating in steps often helps with this process.

In the next blog post, we will provide prescriptive guidance on how to design and build a unified and global SOC using AWS services and AWS Partner Network (APN) solutions.

Learn more:

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Stuart Gregg

Stuart Gregg

Stuart enjoys providing thought leadership and being a trusted advisor to customers. In his spare time, Stuart can be seen either training for an Ironman or snacking.

Ryan Dsouza

Ryan Dsouza

Ryan is a Principal IIoT Security Solutions Architect at AWS. Based in New York City, Ryan helps customers design, develop, and operate more secure, scalable, and innovative IIoT solutions using AWS capabilities to deliver measurable business outcomes. Ryan has over 25 years of experience in multiple technology disciplines and industries and is passionate about bringing security to connected devices.

A phased approach towards a complex HITRUST r2 validated assessment

Post Syndicated from Abdul Javid original https://aws.amazon.com/blogs/security/a-phased-approach-towards-a-complex-hitrust-r2-validated-assessment/

Health Information Trust Alliance (HITRUST) offers healthcare organizations a comprehensive and standardized approach to information security, privacy, and compliance. HITRUST Common Security Framework (HITRUST CSF) can be used by organizations to establish a robust security program, ensure patient data privacy, and assist with compliance with industry regulations. HITRUST CSF enhances security, streamlines compliance efforts, reduces risk, and contributes to overall security resiliency and the trustworthiness of healthcare entities in an increasingly challenging cybersecurity landscape.

While HITRUST primarily focuses on the healthcare industry, its framework and certification program are adaptable and applicable to other industries. The HITRUST CSF is a set of controls and requirements that organizations must comply with to achieve HITRUST certification. The HITRUST R2 assessment is the process by which organizations are evaluated against the requirements of the HITRUST CSF. During the assessment, an independent third party assessor examines the organization’s technical security controls, operational policies and procedures, and the implementation of all controls to determine if they meet the specified HITRUST requirements.

HITRUST r2 validated assessment certification is a comprehensive process that involves meeting numerous assessment requirements. The number of requirements can vary significantly, ranging from 500 to 2,000 depending on your environment’s risk factors and regulatory requirements. Attempting to address all of these requirements simultaneously especially when migrating systems to Amazon Web Services (AWS) can be overwhelming. By using a strategy of separating your compliance journey into environments and applications, you can streamline the process and achieve HITRUST compliance more efficiently and within a realistic timeframe.

In this blog post, we start by exploring the HITRUST domain structure, highlighting the security objective of each domain. We then show how you can use AWS configurable services to help meet these objectives.

Lastly, we present a simple and practical reference architecture with an AWS multi-account implementation that you can use as the foundation for hosting your AWS application, highlighting the phased approach for HITRUST compliance. Please note that this blog is intended to assist with using AWS services in a manner that supports an organization’s HITRUST compliance, but a HITRUST assessment is at an organizational level and involves controls that extend beyond the organization’s use of AWS.

HITRUST certification journey – Scope applications systems on AWS infrastructure:

The HITRUST controls needed for certification are structured within 19 HITRUST domains, covering a wide range of technical and administrative control requirements. To efficiently manage the scope of your certification assessment, start by focusing on the AWS landing zone, which serves as a critical foundational infrastructure component for running applications. When establishing the AWS landing zone, verify that it aligns with the AWS HITRUST security control requirements that are dependent on the scope of your assessment. Note that these 19 domains are a combination of technical controls and foundational administrative controls.

After you’ve set up a HITRUST compliant landing zone, you can begin evaluating your applications for HITRUST compliance as you migrate them to AWS. When you expand and migrate applications to the HITRUST-certified AWS landing zone assessed by your third party assessor, you can inherit the HITRUST controls required for application assessment directly from the landing zone. This simplifies and narrows the scope of your assessment activities.

Figure 1 that follows shows the two key phases and how a bottom-up phased approach can be structured with related HITRUST controls.

Figure 1: HITRUST Phase 1 and Phase 2 high-level components

Figure 1: HITRUST Phase 1 and Phase 2 high-level components

The diagram illustrates:

  • An AWS landing zone environment as Phase 1 and its related HITRUST domain controls
  • An application system as Phase 2 and its related application system specific controls

HITRUST domain security objectives:

The HITRUST CSF based certification consists of 19 domains, which are broad categories that encompass various aspects of information security and privacy controls. These domains serve as a framework for your organization to assess and enhance its security posture. These domains cover a wide range of controls and practices related to information security, privacy, risk management, and compliance. Each domain consists of a set of control objectives and requirements that your organization must meet to achieve HITRUST certification.

The following table lists each domain, the key security objectives expected, and the AWS configurable services relevant to the security objectives. These are listed as a reference to give you an idea of the scope of each domain; the actual services and tools to meet specific HITRUST requirements will vary depending upon your scope and its HITRUST requirements.

Note: The information in this post is a general guideline and recommendation based on a phased approach for HITRUST r2 validated assessment. The examples are based on the information available at the time of publication and are not a full solution.

HITRUST domains, security objectives, and related AWS services

HITRUST domain Summary of key security objectives expected in HITRUST domains Related AWS configurable services
1. Information Protection Program
  • Implement information security management program.
  • Verify role suitability for employees, contractors, and third-party users.
  • Provide management guidance aligned with business goals and regulations.
  • Safeguard an organization’s information and assets.
  • Enhance awareness of information security among stakeholders.
AWS Artifact
AWS Service Catalog
AWS Config
Amazon Cybersecurity Awareness Training
2. Endpoint Protection
  • Protect information and software from unauthorized or malicious code.
  • Safeguard information in networks and the supporting network infrastructure
AWS Systems Manager
AWS Config
Amazon Inspector
AWS Shield
AWS WAF
3. Portable Media Security
  • Ensure the protection of information assets, prevent unauthorized disclosure, alteration, deletion, or harm, and maintain uninterrupted business operations.
AWS Identity and Access Management (IAM)
Amazon Simple Storage Service (Amazon S3)
AWS Key Management Service (AWS KMS)
AWS CloudTrail
Amazon Macie
Amazon Cognito
Amazon Workspaces Family
4. Mobile Device Security
  • Ensure information security while using mobile computing devices and remote work facilities.
AWS Database Migration Service (AWS DMS)
AWS IoT Device Defender
AWS Snowball
AWS Config
5. Wireless Security
  • Ensure the safeguarding of information within networks and the security of the underlying network infrastructure.
AWS Certificate Manager (ACM)
6. Configuration Management
  • Ensure adherence to organizational security policies and standards for information systems.
  • Control system files, access, and program source code for security.
  • Document, maintain, and provide operating procedures to users.
  • Strictly control project and support environments for secure development of application system software and information.
AWS Config
AWS Trusted Advisor
Amazon CloudWatch
AWS Security Hub
Systems Manager
7. Vulnerability Management
  • Implement effective and repeatable technical vulnerability management to mitigate risks from exploited vulnerabilities.
  • Establish ownership and defined responsibilities for the protection of information assets within management.
  • Design controls in applications, including user-developed ones, to prevent errors, loss, unauthorized modification, or misuse of information. These controls should encompass input data validation, internal processing, and output data.
Amazon Inspector
CloudWatch
Security Hub
8. Network Protection
  • Secure information across networks and network infrastructure.
  • Prevent unauthorized access to networked services.
  • Ensure unauthorized access prevention to information in application systems.
  • Implement controls within applications to prevent errors, loss, unauthorized modification, or misuse of information.
Amazon Route 53
AWS Control Tower
Amazon Virtual Private Cloud (Amazon VPC)
AWS Transit Gateway
Network Load Balancer
AWS Direct Connect
AWS Site-to-Site VPN
AWS CloudFormation
AWS WAF
ACM
9. Transmission Protection
  • Ensure robust protection of information within networks and their underlying infrastructure.
  • Facilitate secure information exchange both internally and externally, adhering to applicable laws and agreements.
  • Ensure the security of electronic commerce services and their use.
  • Employ cryptographic methods to ensure confidentiality, authenticity, and integrity of information.
  • Formulate cryptographic control policies and institute key management to bolster their implementation.
Systems Manager
ACM
10. Password Management
  • Register, track, and periodically validate authorized user accounts to prevent unauthorized access to information systems.
AWS Secrets Manager, Systems Manager Parameter Store, AWS KMS
11. Access Control
  • Monitor and log security events to detect unauthorized activities in compliance with legal requirements.
  • Prevent unauthorized access, compromise, or theft of information, assets, and user entry.
  • Safeguard against unauthorized access to networked services, operating systems, and application information.
  • Manage access rights and asset recovery for terminated or transferred personnel and contractors.
  • Ensure adherence to applicable laws, regulations, contracts, and security requirements throughout information systems’ lifecycle.
IAM
AWS Resource Access Manager (AWS RAM)
Amazon GuardDuty
AWS Identity Center
12. Audit Logging & Monitoring
  • Comply with laws, regulations, contracts, and security mandates in information systems’ design, operation, use, and management.
  • Document, maintain, and share operating procedures with relevant users.
  • Monitor, record, and uncover unauthorized information processing in line with legal requirements.
AWS Control Tower
Amazon S3
CloudTrail
GuardDuty
AWS Config
CloudWatch
Amazon VPC Flow logs
Amazon OpenSearch Service
13. Education, Training and Awareness
  • Secure information when using mobile devices and teleworking.
  • Make employees, contractors, and third-party users aware of security threats, and responsibilities and reduce human error.
  • Ensure information systems comply with laws, regulations, contracts, and security requirements.
  • Assign ownership and defined responsibilities for protecting information assets.
  • Protect information and software integrity from unauthorized code.
  • Securely exchange information within and outside the organization, following relevant laws and agreements.
  • Develop strategies to counteract business interruptions, protect critical processes, and resume them promptly after system failures or disasters.
Security Hub
Amazon Cybersecurity Awareness Training
Trusted Advisor
14. Third-Party Assurance
  • Safeguard information and assets by mitigating risks linked to external products or services.
  • Verify third-party service providers adhere to security requirements and maintain agreed upon service levels.
  • Enforce stringent controls over development, project, and support environments to ensure software and information security.
AWS Artifact
AWS Service Organization Controls (SOC) Reports
ISO27001 reports
15. Incident Management
  • Address security events and vulnerabilities promptly for timely correction.
  • Foster awareness among employees, contractors, and third-party users to reduce human errors.
  • Consistently manage information security incidents for effective response.
  • Handle security events to facilitate timely corrective measures.
AWS Incident Detection and Response
Security Hub
Amazon Inspector
CloudTrail
AWS Config
Amazon Simple Notification Service (Amazon SNS)
GuardDuty
AWS WAF
Shield
CloudFormation
16. Business Continuity & Disaster Recovery
  • Maintain, protect, and make organizational information available.
  • Develop strategies and plans to prevent disruptions to business activities, safeguard critical processes from system failures or disasters, and ensure their prompt recovery.
AWS Backup & Restore
CloudFormation
Amazon Aurora
CrossRegion replication
AWS Backup
Disaster Recovery: Pilot Light, Warm Standby, Multi Site Active-Active
17. Risk Management
  • Integrate security as a vital element within information systems.
  • Develop and implement a risk management program encompassing risk assessment, mitigation, and evaluation
Trusted Advisor
AWS Config Rules
18. Physical & Environmental Security
  • Secure the organization’s premises and information from unauthorized physical access, damage, and interference.
  • Prevent unauthorized access to networked services.
  • Safeguard assets, prevent loss, damage, theft, or compromise, and ensure uninterrupted organizational activities.
  • Protect information assets from unauthorized disclosure, modification, removal, or destruction, and prevent interruptions to business activities.
AWS Data Centers
Amazon CloudFront
AWS Regions and Global Infrastructure
19. Data Protection & Privacy
  • Ensure the security of the organization’s information and assets when using external products or services.
  • Ensure planning, operation, use, and control of information systems align with applicable laws, regulations, contracts, and security requirements.
Amazon S3
AWS KMS
Aurora
OpenSearch Service
AWS Artifact
Macie

Note: You can use AWS HITRUST-certified services to support your HITRUST compliance requirements. Use of these services in their default state doesn’t automatically ensure HITRUST certifiability. You must demonstrate compliance through formal formulation of policies, procedures, and implementation tailored to your scope, which involves configuring and customizing AWS HITRUST certified services to align precisely with HITRUST requirements within your scope and involves implementation of controls outside of the scope of the use of AWS services (such as appropriate organization-wide policies and procedures).

HITRUST phased approach – Reference architecture:

Figure 2 shows the recommended HITRUST Phase 1 and Phase 2 accounts and components within a landing zone.

Figure 2: HITRUST Phases 1 and 2 architecture including accounts and components

Figure 2: HITRUST Phases 1 and 2 architecture including accounts and components

The reference architecture shown in Figure 2 illustrates:

  • A high-level structure of AWS accounts arranged in HITRUST Phase 1 and Phase 2
  • The accounts in HITRUST Phase 1 include:
    • Management account: The management account in the AWS landing zone is the primary account responsible for governing and managing the entire AWS environment.
    • Security account: The security account is dedicated to security and compliance functions, providing a centralized location for security-related tools and monitoring.
    • Central logging account: This account is designed for centralized logging and storage of logs from all other accounts, aiding in security analysis and troubleshooting.
    • Central audit: The central audit account is used for compliance monitoring, logging audit events, and verifying adherence to security standards.
    • DevOps account: DevOps accounts are used for software development and deployment, enabling continuous integration and delivery (CI/CD) processes.
    • Networking account: Networking accounts focus on network management, configuration, and monitoring to support reliable connectivity within the AWS environment.
    • DevSecOps account: DevSecOps accounts combine development, security, and operations to embed security practices throughout the software development lifecycle.
    • Shared services account: Shared services accounts host common resources, such as IAM services, that are shared across other accounts for centralized management.

The account group for HITRUST Phase 2 includes:

  • Tenant A – sample application workloads
  • Tenant B – sample application workloads

HITRUST Phase 1 – HITRUST foundational landing zone assessment phase:

In this phase you define the scope of assessment, including the specific AWS landing zone components and configurations that must be HITRUST compliant. The primary focus here is to evaluate the foundational infrastructure’s compliance with HITRUST controls. This involves a comprehensive review of policies and procedures, and implementation of all requirements within the landing zone scope. Assessing this phase separately enables you to verify that your foundational infrastructure adheres to HITRUST controls. Some of the policies, procedures, and configurations that are HITRUST assessed in this phase can be inherited across multiple applications’ assessments in later phases. Assessing this infrastructure once and then inheriting these controls for applications can be more efficient than assessing each application individually.

By establishing a secure and compliant foundation at the start, you can plan application assessments in later phases, making it simpler for subsequent applications to adhere to HITRUST requirements. This can streamline the compliance process and reduce the overall time and effort required. By assessing the landing zone separately, you can identify and address compliance gaps or issues in your foundational infrastructure, reducing the risk of non-compliance for the applications built upon it. Use the following high-level technical approach for this phase of assessment.

  1. Build your AWS landing zone with HITRUST controls. See Building a landing zone for more information.
  2. Use AWS and configure services according to the HITRUST requirements that are applicable to your infrastructure scope.
  3. The HITRUST on AWS Quick Start guide is a reference for building HITRUST with one account. You can use the guide as a starting point to build a multi account architecture.

HITRUST Phase 2 – HITRUST application assessment phase:

During this phase, you examine your AWS workload application accounts to conduct HITRUST assessments for application systems that are running within the AWS landing zone. You have the option to inherit environment-related controls that have been certified as HITRUST compliant within the landing zone in the previous phase.

The following key steps are recommended in this phase:

  1. Readiness assessment for application scope: Conduct a thorough readiness assessment focused on the application scope, and define boundaries with scoped applications (AWS workload accounts).
  2. HITRUST application controls: Gather specific HITRUST requirements for application scope by creating a HITRUST object for the application scope.
  3. Scoped requirements analysis: Analyze requirements and use requirements that can be inherited from Phase 1 of the infrastructure assessment.
  4. Gap analysis: Work with subject matter experts to conduct a gap analysis, and develop policies, procedures, and implementations for application specific controls.
  5. Remediation: Remediate the gaps identified during the gap analysis activity.
  6. Formal r2 assessment: Work with a third-party assessor to initiate a formal r2 validated assessment with HITRUST.

Conclusion

By breaking the compliance process into distinct phases, you can concentrate your resources on specific areas and prioritize essential assets accordingly. This approach supports a focused strategy, systematically addressing critical controls, and helping you to fulfill compliance requirements in a scalable manner. Obtaining the initial certification for the infrastructure and platform layers establishes a robust foundational architecture for subsequent phases, which involve application systems.

Earning certification at each phase provides tangible evidence of progress in your compliance journey. This achievement instills confidence in both internal and external stakeholders, affirming your organization’s commitment to security and compliance.

For guidance on achieving, maintaining, and automating compliance in the cloud, reach out to AWS Security Assurance Services (AWS SAS) or your account team. AWS SAS is a PCI QSAC and HITRUST External Assessor that can help by tying together applicable audit standards to AWS service-specific features and functionality. They can help you build on frameworks such as PCI DSS, HITRUST CSF, NIST, SOC 2, HIPAA, ISO 27001, GDPR, and CCPA.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Security, Identity, & Compliance re:Post or contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Abdul Javid

Abdul Javid

Abdul is a Senior Security Assurance Consultant and PCI DSS Qualified Security Assessor with AWS Security Assurance Services, and has more than 25 years of IT governance, operations, security, risk, and compliance experience. Abdul leverages his experience and knowledge to advise AWS customers with guidance and advice on their compliance journey. Abdul earned an M.S. in Computer Science from IIT, Chicago and holds various industry recognized sought after certifications in security and program and risk management from prominent organizations like AWS, HITRUST, ISACA, PMI, PCI DSS, and ISC2.

Cate Ciccolone

Cate Ciccolone

Cate is a Senior Security Consultant for Amazon Web Services (AWS) where she provides technical and advisory consulting services to global healthcare organizations to help them secure their regulated workloads, minimize risk, and meet compliance goals. Her experience spans cybersecurity engineering, healthcare compliance, electronic health record architecture, and clinical application security. Cate is an AWS Certified Solutions Architect and holds several certifications including EC-Council Certified Incident Handler (E|CIH) and HITRUST Certified Practitioner (CCSFP).

Enable cost-efficient operational analytics with Amazon OpenSearch Ingestion

Post Syndicated from Mikhail Vaynshteyn original https://aws.amazon.com/blogs/big-data/enable-cost-efficient-operational-analytics-with-amazon-opensearch-ingestion/

As the scale and complexity of microservices and distributed applications continues to expand, customers are seeking guidance for building cost-efficient infrastructure supporting operational analytics use cases. Operational analytics is a popular use case with Amazon OpenSearch Service. A few of the defining characteristics of these use cases are ingesting a high volume of time series data and a relatively low volume of querying, alerting, and running analytics on ingested data for real-time insights. Although OpenSearch Service is capable of ingesting petabytes of data across storage tiers, you still have to provision capacity to migrate between hot and warm tiers. This adds to the cost of provisioned OpenSearch Service domains.

The time series data often contains logs or telemetry data from various sources with different values and needs. That is, logs from some sources need to be available in a hot storage tier longer, whereas logs from other sources can tolerate a delay in querying and other requirements. Until now, customers were building external ingestion systems with the Amazon Kinesis family of services, Amazon Simple Queue Service (Amazon SQS), AWS Lambda, custom code, and other similar solutions. Although these solutions enable ingestion of operational data with various requirements, they add to the cost of ingestion.

In general, operational analytics workloads use anomaly detection to aid domain operations. This assumes that the data is already present in OpenSearch Service and the cost of ingestion is already borne.

With the addition of a few recent features of Amazon OpenSearch Ingestion, a fully managed serverless pipeline for OpenSearch Service, you can effectively address each of these cost points and build a cost-effective solution. In this post, we outline a solution that does the following:

  • Uses conditional routing of Amazon OpenSearch Ingestion to separate logs with specific attributes and store those, for example, in Amazon OpenSearch Service and archive all events in Amazon S3 to query with Amazon Athena
  • Uses in-stream anomaly detection with OpenSearch Ingestion, thereby removing the cost associated with compute needed for anomaly detection after ingestion

In this post, we use a VPC flow logs use case to demonstrate the solution. The solution and pattern presented in this post is equally applicable to larger operational analytics and observability use cases.

Solution overview

We use VPC flow logs to capture IP traffic and trigger processing notifications to the OpenSearch Ingestion pipeline. The pipeline filters the data, routes the data, and detects anomalies. The raw data will be stored in Amazon S3 for archival purposes, then the pipeline will detect anomalies in the data in near-real time using the Random Cut Forest (RCF) algorithm and send those data records to OpenSearch Service. The raw data stored in Amazon S3 can be inexpensively retained for an extended period of time using tiered storage and queried using the Athena query engine, and also visualized using Amazon QuickSight or other data visualization services. Although this walkthrough uses VPC flow log data, the same pattern applies for use with AWS CloudTrail, Amazon CloudWatch, any log files as well as any OpenTelemetry events, and custom producers.

The following is a diagram of the solution that we configure in this post.

In the following sections, we provide a walkthrough for configuring this solution.

The patterns and procedures presented in this post have been validated with the current version of OpenSearch Ingestion and the Data Prepper open-source project version 2.4.

Prerequisites

Complete the following prerequisite steps:

  1. We will be using a VPC for demonstration purposes for generating data. Set up the VPC flow logs to publish logs to an S3 bucket in text format. To optimize S3 storage costs, create a lifecycle configuration on the S3 bucket to transition the VPC flow logs to different tiers or expire processed logs. Make a note of the S3 bucket name you configured to use in later steps.
  2. Set up an OpenSearch Service domain. Make a note of the domain URL. The domain can be either public or VPC based, which is the preferred configuration.
  3. Create an S3 bucket for storing archived events, and make a note of S3 bucket name. Configure a resource-based policy allowing OpenSearch Ingestion to archive logs and Athena to read the logs.
  4. Configure an AWS Identity and Access Management (IAM) role or separate IAM roles allowing OpenSearch Ingestion to interact with Amazon SQS and Amazon S3. For instructions, refer to Configure the pipeline role.
  5. Configure Athena or validate that Athena is configured on your account. For instructions, refer to Getting started.

Configure an SQS notification

VPC flow logs will write data in Amazon S3. After each file is written, Amazon S3 will send an SQS notification to notify the OpenSearch Ingestion pipeline that the file is ready for processing.

If the data is already stored in Amazon S3, you can use the S3 scan capability for a one-time or scheduled loading of data through the OpenSearch Ingestion pipeline.

Use AWS CloudShell to issue the following commands to create the SQS queues VpcFlowLogsNotifications and VpcFlowLogsNotifications-DLQ that we use for this walkthrough.

Create a dead-letter queue with the following code

export SQS_DLQ_URL=$(aws sqs create-queue --queue-name VpcFlowLogsNotifications-DLQ | jq -r '.QueueUrl')

echo $SQS_DLQ_URL 

export SQS_DLQ_ARN=$(aws sqs get-queue-attributes --queue-url $SQS_DLQ_URL --attribute-names QueueArn | jq -r '.Attributes.QueueArn') 

echo $SQS_DLQ_ARN

Create an SQS queue to receive events from Amazon S3 with the following code:

export SQS_URL=$(aws sqs create-queue --queue-name VpcFlowLogsNotification --attributes '{
"RedrivePolicy": 
"{\"deadLetterTargetArn\":\"'$SQS_DLQ_ARN'\",\"maxReceiveCount\":\"2\"}", 
"Policy": 
  "{\"Version\":\"2012-10-17\",\"Statement\":[{\"Effect\":\"Allow\",\"Principal\":{\"Service\":\"s3.amazonaws.com\"}, \"Action\":\"SQS:SendMessage\",\"Resource\":\"*\"}]}" 
}' | jq -r '.QueueUrl')

echo $SQS_URL

To configure the S3 bucket to send events to the SQS queue, use the following code (provide the name of your S3 bucket used for storing VPC flow logs):

aws s3api put-bucket-notification-configuration --bucket __BUCKET_NAME__ --notification-configuration '{
     "QueueConfigurations": [
         {
             "QueueArn": "'$SQS_URL'",
             "Events": [
                 "s3:ObjectCreated:*"
             ]
         }
     ]
}'

Create the OpenSearch Ingestion pipeline

Now that you have configured Amazon SQS and the S3 bucket notifications, you can configure the OpenSearch Ingestion pipeline.

  1. On the OpenSearch Service console, choose Pipelines under Ingestion in the navigation pane.
  2. Choose Create pipeline.

  1. For Pipeline name, enter a name (for this post, we use stream-analytics-pipeline).
  2. For Pipeline configuration, enter the following code:
version: "2"
entry-pipeline:
  source:
     s3:
       notification_type: sqs
       compression: gzip
       codec:
         newline:
       sqs:
         queue_url: "<strong>__SQS_QUEUE_URL__</strong>"
         visibility_timeout: 180s
       aws:
        region: "<strong>__REGION__</strong>"
        sts_role_arn: "<strong>__STS_ROLE_ARN__</strong>"
  
  processor:
  sink:
    - pipeline:
        name: "archive-pipeline"
    - pipeline:
        name: "data-processing-pipeline"

data-processing-pipeline:
    source: 
        pipeline:
            name: "entry-pipeline"
    processor:
    - grok:
        tags_on_match_failure: [ "grok_match_failure" ]
        match:
          message: [ "%{VPC_FLOW_LOG}" ]
    route:
        - icmp_traffic: '/protocol == 1'
    sink:
        - pipeline:
            name : "icmp-pipeline"
            routes:
                - "icmp_traffic"
        - pipeline:
            name: "analytics-pipeline"
    

archive-pipeline:
  source:
    pipeline:
      name: entry-pipeline
  processor:
  sink:
    - s3:
        aws:
          region: "<strong>__REGION__</strong>"
          sts_role_arn: "<strong>__STS_ROLE_ARN__</strong>"
        max_retries: 16
        bucket: "<strong>__AWS_S3_BUCKET_ARCHIVE__</strong>"
        object_key:
          path_prefix: "vpc-flow-logs-archive/year=%{yyyy}/month=%{MM}/day=%{dd}/"
        threshold:
          maximum_size: 50mb
          event_collect_timeout: 300s
        codec:
          parquet:
            auto_schema: true
      
analytics-pipeline:
  source:
    pipeline:
      name: "data-processing-pipeline"
  processor:
    - drop_events:
        drop_when: "hasTags(\"grok_match_failure\") or \"/log-status\" == \"NODATA\""
    - date:
        from_time_received: true
        destination: "@timestamp"
    - aggregate:
        identification_keys: ["srcaddr", "dstaddr"]
        action:
          tail_sampler:
            percent: 20.0
            wait_period: "60s"
            condition: '/action != "ACCEPT"'
    - anomaly_detector:
        identification_keys: ["srcaddr","dstaddr"]
        keys: ["bytes"]
        verbose: true
        mode:
          random_cut_forest:
  sink:
    - opensearch:
        hosts: [ "<strong>__AMAZON_OPENSEARCH_DOMAIN_URL__</strong>" ]
        index: "flow-logs-anomalies"
        aws:
          sts_role_arn: "<strong>__STS_ROLE_ARN__</strong>"
          region: "<strong>__REGION__</strong>"
          
icmp-pipeline:
  source:
    pipeline:
      name: "data-processing-pipeline"
  processor:
  sink:
    - opensearch:
        hosts: [ "<strong>__AMAZON_OPENSEARCH_DOMAIN_URL__</strong>" ]
        index: "sensitive-icmp-traffic"
        aws:
          sts_role_arn: "<strong>__STS_ROLE_ARN__</strong>"
          region: "<strong>__REGION__</strong>"</code>

Replace the variables in the preceding code with resources in your account:

    • __SQS_QUEUE_URL__ – URL of Amazon SQS for Amazon S3 events
    • __STS_ROLE_ARN__ – AWS Security Token Service (AWS STS) roles for resources to assume
    • __AWS_S3_BUCKET_ARCHIVE__ – S3 bucket for archiving processed events
    • __AMAZON_OPENSEARCH_DOMAIN_URL__ – URL of OpenSearch Service domain
    • __REGION__ – Region (for example, us-east-1)
  1. In the Network settings section, specify your network access. For this walkthrough, we are using VPC access. We provided the VPC and private subnet locations that have connectivity with the OpenSearch Service domain and security groups.
  2. Leave the other settings with default values, and choose Next.
  3. Review the configuration changes and choose Create pipeline.

It will take a few minutes for OpenSearch Service to provision the environment. While the environment is being provisioned, we’ll walk you through the pipeline configuration. Entry-pipeline listens for SQS notifications about newly arrived files and triggers the reading of VPC flow log compressed files:

…
entry-pipeline:
  source:
     s3:
…

The pipeline branches into two sub-pipelines. The first stores original messages for archival purposes in Amazon S3 in read-optimized Parquet format; the other applies analytics routes events to the OpenSearch Service domain for fast querying and alerting:

…
  sink:
    - pipeline:
        name: "archive-pipeline"
    - pipeline:
        name: "data-processing-pipeline"
… 

The pipeline archive-pipeline aggregates messages in 50 MB chunks or every 60 seconds and writes a Parquet file to Amazon S3 with the schema inferred from the message. Also, a prefix is added to help with partitioning and query optimization when reading a collection of files using Athena.

…
sink:
    - s3:
…
        object_key:
          path_prefix: " vpc-flow-logs-archive/year=%{yyyy}/month=%{MM}/day=%{dd}/"
        threshold:
          maximum_size: 50mb
          event_collect_timeout: 300s
        codec:
          parquet:
            auto_schema: true
…

Now that we have reviewed the basics, we focus on the pipeline that detects anomalies and sends only high-value messages that deviate from the norm to OpenSearch Service. It also stores Internet Control Message Protocols (ICMP) messages in OpenSearch Service.

We applied a grok processor to parse the message using a predefined regex for parsing VPC flow logs, and also tagged all unparsable messages with the grok_match_failure tag, which we use to remove headers and other records that can’t be parsed:

…
    processor:
    - grok:
        tags_on_match_failure: [ "grok_match_failure" ]
        match:
          message: [ "%{VPC_FLOW_LOG}" ]
…

We then routed all messages with the protocol identifier 1 (ICMP) to icmp-pipeline and all messages to analytics-pipeline for anomaly detection:

…
   route:
        - icmp_traffic: '/protocol == 1'
    sink:
        - pipeline:
            name : "icmp-pipeline"
            routes:
                - "icmp_traffic"
        - pipeline:
            name: "analytics-pipeline"
…

In the analytics pipeline, we dropped all records that can’t be parsed using the hasTags method based on the tag that we assigned at the time of parsing. We also removed all records that don’t contains useful data for anomaly detection.

…
  - drop_events:
        drop_when: "hasTags(\"grok_match_failure\") or \"/log-status\" == \"NODATA\""		
…

Then we applied probabilistic sampling using the tail_sampler processor for all accepted messages grouped by source and destination addresses and sent those to the sink with all messages that were not accepted. This helps reduce the volume of messages within the selected cardinality keys, with a focus on all messages that weren’t accepted, and keeps a sample representation of messages that were accepted.

…
aggregate:
        identification_keys: ["srcaddr", "dstaddr"]
        action:
          tail_sampler:
            percent: 20.0
            wait_period: "60s"
            condition: '/action != "ACCEPT"'
…

Then we used the anomaly detector processor to identify anomalies within the cardinality key pairs or source and destination addresses in our example. The anomaly detector processor creates and trains RCF models for a hashed value of keys, then uses those models to determine whether newly arriving messages have an anomaly based on the trained data. In our demonstration, we use bytes data to detect anomalies:

…
anomaly_detector:
        identification_keys: ["srcaddr","dstaddr"]
        keys: ["bytes"]
        verbose: true
        mode:
          random_cut_forest:
…

We set verbose:true to instruct the detector to emit the message every time an anomaly is detected. Also, for this walkthrough, we used a non-default sample_size for training the model.

When anomalies are detected, the anomaly detector returns a complete record and adds

"deviation_from_expected":value,"grade":value attributes that signify the deviation value and severity of the anomaly. These values can be used to determine routing of such messages to OpenSearch Service, and use per-document monitoring capabilities in OpenSearch Service to alert on specific conditions.

Currently, OpenSearch Ingestion creates up to 5,000 distinct models based on cardinality key values per compute unit. This limit is observed using the anomaly_detector.RCFInstances.value CloudWatch metric. It’s important to select a cardinality key-value pair to avoid exceeding this constraint. As development of the Data Prepper open-source project and OpenSearch Ingestion continues, more configuration options will be added to offer greater flexibility around model training and memory management.

The OpenSearch Ingestion pipeline exposes the anomaly_detector.cardinalityOverflow.count metric through CloudWatch. This metric indicates a number of key value pairs that weren’t run by the anomaly detection processor during a period of time as the maximum number of RCFInstances per compute unit was reached. To avoid this constraint, a number of compute units can be scaled out to provide additional capacity for hosting additional instances of RCFInstances.

In the last sink, the pipeline writes records with detected anomalies along with deviation_from_expected and grade attributes to the OpenSearch Service domain:

…
sink:
    - opensearch:
        hosts: [ "__AMAZON_OPENSEARCH_DOMAIN_URL__" ]
        index: "anomalies"
…

Because only anomaly records are being routed and written to the OpenSearch Service domain, we are able to significantly reduce the size of our domain and optimize the cost of our sample observability infrastructure.

Another sink was used for storing all ICMP records in a separate index in the OpenSearch Service domain:

…
sink:
    - opensearch:
        hosts: [ "__AMAZON_OPENSEARCH_DOMAIN_URL__" ]
        index: " sensitive-icmp-traffic"
…

Query archived data from Amazon S3 using Athena

In this section, we review the configuration of Athena for querying archived events data stored in Amazon S3. Complete the following steps:

  1. Navigate to the Athena query editor and create a new database called vpc-flow-logs-archive-database using the following command:
CREATE DATABASE `vpc-flow-logs-archive`
  1. 2. On the Database menu, choose vpc-flow-logs-archive.
  2. In the query editor, enter the following command to create a table (provide the S3 bucket used for archiving processed events). For simplicity, for this walkthrough, we create a table without partitions.
CREATE EXTERNAL TABLE `vpc-flow-logs-data`(
  `message` string)
ROW FORMAT SERDE 
  'org.apache.hadoop.hive.ql.io.parquet.serde.ParquetHiveSerDe' 
STORED AS INPUTFORMAT 
  'org.apache.hadoop.hive.ql.io.parquet.MapredParquetInputFormat' 
OUTPUTFORMAT 
  'org.apache.hadoop.hive.ql.io.parquet.MapredParquetOutputFormat'
LOCATION
  's3://__AWS_S3_BUCKET_ARCHIVE__'
TBLPROPERTIES (
  'classification'='parquet', 
  'compressionType'='none'
)
  1. Run the following query to validate that you can query the archived VPC flow log data:
SELECT * FROM "vpc-flow-logs-archive"."vpc-flow-logs-data" LIMIT 10;

Because archived data is stored in its original format, it helps avoid issues related to format conversion. Athena will query and display records in the original format. However, it’s ideal to interact only with a subset of columns or parts of the messages. You can use the regexp_split function in Athena to split the message in the columns and retrieve certain columns. Run the following query to see the source and destination address groupings from the VPC flow log data:

SELECT srcaddr, dstaddr FROM (
   SELECT regexp_split(message, ' ')[4] AS srcaddr, 
          regexp_split(message, ' ')[5] AS dstaddr, 
          regexp_split(message, ' ')[14] AS status  FROM "vpc-flow-logs-archive"."vpc-flow-logs-data" 
) WHERE status = 'OK' 
GROUP BY srcaddr, dstaddr 
ORDER BY srcaddr, dstaddr LIMIT 10;

This demonstrated that you can query all events using Athena, where archived data in its original raw format is used for the analysis. Athena is priced per data scanned. Because the data is stored in a read-optimized format and partitioned, it enables further cost-optimization around on-demand querying of archived streaming and observability data.

Clean up

To avoid incurring future charges, delete the following resources created as part of this post:

  • OpenSearch Service domain
  • OpenSearch Ingestion pipeline
  • SQS queues
  • VPC flow logs configuration
  • All data stored in Amazon S3

Conclusion

In this post, we demonstrated how to use OpenSearch Ingestion pipelines to build a cost-optimized infrastructure for log analytics and observability events. We used routing, filtering, aggregation, and anomaly detection in an OpenSearch Ingestion pipeline, enabling you to downsize your OpenSearch Service domain and create a cost-optimized observability infrastructure. For our example, we used a data sample with 1.5 million events with a pipeline distilling to 1,300 events with predicted anomalies based on source and destination IP pairs. This metric demonstrates that the pipeline identified that less than 0.1% of events were of high importance, and routed those to OpenSearch Service for visualization and alerting needs. This translates to lower resource utilization in OpenSearch Service domains and can lead to provisioning of smaller OpenSearch Service environments.

We encourage you to use OpenSearch Ingestion pipelines to create your purpose-built and cost-optimized observability infrastructure that uses OpenSearch Service for storing and alerting on high-value events. If you have comments or feedback, please leave them in the comments section.


About the Authors

Mikhail Vaynshteyn is a Solutions Architect with Amazon Web Services. Mikhail works with healthcare and life sciences customers to build solutions that help improve patients’ outcomes. Mikhail specializes in data analytics services.
Muthu Pitchaimani is a Search Specialist with Amazon OpenSearch Service. He builds large-scale search applications and solutions. Muthu is interested in the topics of networking and security, and is based out of Austin, Texas.

Mask and redact sensitive data published to Amazon SNS using managed and custom data identifiers

Post Syndicated from Otavio Ferreira original https://aws.amazon.com/blogs/security/mask-and-redact-sensitive-data-published-to-amazon-sns-using-managed-and-custom-data-identifiers/

Today, we’re announcing a new capability for Amazon Simple Notification Service (Amazon SNS) message data protection. In this post, we show you how you can use this new capability to create custom data identifiers to detect and protect domain-specific sensitive data, such as your company’s employee IDs. Previously, you could only use managed data identifiers to detect and protect common sensitive data, such as names, addresses, and credit card numbers.

Overview

Amazon SNS is a serverless messaging service that provides topics for push-based, many-to-many messaging for decoupling distributed systems, microservices, and event-driven serverless applications. As applications become more complex, it can become challenging for topic owners to manage the data flowing through their topics. These applications might inadvertently start sending sensitive data to topics, increasing regulatory risk. To mitigate the risk, you can use message data protection to protect sensitive application data using built-in, no-code, scalable capabilities.

To discover and protect data flowing through SNS topics with message data protection, you can associate data protection policies to your topics. Within these policies, you can write statements that define which types of sensitive data you want to discover and protect. Within each policy statement, you can then define whether you want to act on data flowing inbound to an SNS topic or outbound to an SNS subscription, the AWS accounts or specific AWS Identity and Access Management (IAM) principals the statement applies to, and the actions you want to take on the sensitive data found.

Now, message data protection provides three actions to help you protect your data. First, the audit operation reports on the amount of sensitive data found. Second, the deny operation helps prevent the publishing or delivery of payloads that contain sensitive data. Third, the de-identify operation can mask or redact the sensitive data detected. These no-code operations can help you adhere to a variety of compliance regulations, such as Health Insurance Portability and Accountability Act (HIPAA), Federal Risk and Authorization Management Program (FedRAMP), General Data Protection Regulation (GDPR), and Payment Card Industry Data Security Standard (PCI DSS).

This message data protection feature coexists with the message data encryption feature in SNS, both contributing to an enhanced security posture of your messaging workloads.

Managed and custom data identifiers

After you add a data protection policy to your SNS topic, message data protection uses pattern matching and machine learning models to scan your messages for sensitive data, then enforces the data protection policy in real time. The types of sensitive data are referred to as data identifiers. These data identifiers can be either managed by Amazon Web Services (AWS) or custom to your domain.

Managed data identifiers (MDI) are organized into five categories:

In a data protection policy statement, you refer to a managed data identifier using its Amazon Resource Name (ARN), as follows:

{
    "Name": "__example_data_protection_policy",
    "Description": "This policy protects sensitive data in expense reports",
    "Version": "2021-06-01",
    "Statement": [{
        "DataIdentifier": [
            "arn:aws:dataprotection::aws:data-identifier/CreditCardNumber"
        ],
        "..."
    }]
}

Custom data identifiers (CDI), on the other hand, enable you to define custom regular expressions in the data protection policy itself, then refer to them from policy statements. Using custom data identifiers, you can scan for business-specific sensitive data, which managed data identifiers can’t. For example, you can use a custom data identifier to look for company-specific employee IDs in SNS message payloads. Internally, SNS has guardrails to make sure custom data identifiers are safe and that they add only low single-digit millisecond latency to message processing.

In a data protection policy statement, you refer to a custom data identifier using only the name that you have given it, as follows:

{
    "Name": "__example_data_protection_policy",
    "Description": "This policy protects sensitive data in expense reports",
    "Version": "2021-06-01",
    "Configuration": {
        "CustomDataIdentifier": [{
            "Name": "MyCompanyEmployeeId", "Regex": "EID-\d{9}-US"
        }]
    },
    "Statement": [{
        "DataIdentifier": [
            "arn:aws:dataprotection::aws:data-identifier/CreditCardNumber",
            "MyCompanyEmployeeId"
        ],
        "..."
    }]
}

Note that custom data identifiers can be used in conjunction with managed data identifiers, as part of the same data protection policy statement. In the preceding example, both MyCompanyEmployeeId and CreditCardNumber are in scope.

For more information, see Data Identifiers, in the SNS Developer Guide.

Inbound and outbound data directions

In addition to the DataIdentifier property, each policy statement also sets the DataDirection property (whose value can be either Inbound or Outbound) as well as the Principal property (whose value can be any combination of AWS accounts, IAM users, and IAM roles).

When you use message data protection for data de-identification and set DataDirection to Inbound, instances of DataIdentifier published by the Principal are masked or redacted before the payload is ingested into the SNS topic. This means that every endpoint subscribed to the topic receives the same modified payload.

When you set DataDirection to Outbound, on the other hand, the payload is ingested into the SNS topic as-is. Then, instances of DataIdentifier are either masked, redacted, or kept as-is for each subscribing Principal in isolation. This means that each endpoint subscribed to the SNS topic might receive a different payload from the topic, with different sensitive data de-identified, according to the data access permissions of its Principal.

The following snippet expands the example data protection policy to include the DataDirection and Principal properties.

{
    "Name": "__example_data_protection_policy",
    "Description": "This policy protects sensitive data in expense reports",
    "Version": "2021-06-01",
    "Configuration": {
        "CustomDataIdentifier": [{
            "Name": "MyCompanyEmployeeId", "Regex": "EID-\d{9}-US"
        }]
    },
    "Statement": [{
        "DataIdentifier": [
            "MyCompanyEmployeeId",
            "arn:aws:dataprotection::aws:data-identifier/CreditCardNumber"
        ],
        "DataDirection": "Outbound",
        "Principal": [ "arn:aws:iam::123456789012:role/ReportingApplicationRole" ],
        "..."
    }]
}

In this example, ReportingApplicationRole is the authenticated IAM principal that called the SNS Subscribe API at subscription creation time. For more information, see How do I determine the IAM principals for my data protection policy? in the SNS Developer Guide.

Operations for data de-identification

To complete the policy statement, you need to set the Operation property, which informs the SNS topic of the action that it should take when it finds instances of DataIdentifer in the outbound payload.

The following snippet expands the data protection policy to include the Operation property, in this case using the Deidentify object, which in turn supports masking and redaction.

{
    "Name": "__example_data_protection_policy",
    "Description": "This policy protects sensitive data in expense reports",
    "Version": "2021-06-01",
    "Configuration": {
        "CustomDataIdentifier": [{
            "Name": "MyCompanyEmployeeId", "Regex": "EID-\d{9}-US"
        }]
    },
    "Statement": [{
        "Principal": [
            "arn:aws:iam::123456789012:role/ReportingApplicationRole"
        ],
        "DataDirection": "Outbound",
        "DataIdentifier": [
            "MyCompanyEmployeeId",
            "arn:aws:dataprotection::aws:data-identifier/CreditCardNumber"
        ],
        "Operation": { "Deidentify": { "MaskConfig": { "MaskWithCharacter": "#" } } }
    }]
}

In this example, the MaskConfig object instructs the SNS topic to mask instances of CreditCardNumber in Outbound messages to subscriptions created by ReportingApplicationRole, using the MaskWithCharacter value, which in this case is the hash symbol (#). Alternatively, you could have used the RedactConfig object instead, which would have instructed the SNS topic to simply cut the sensitive data off the payload.

The following snippet shows how the outbound payload is masked, in real time, by the SNS topic.

// original message published to the topic:
My credit card number is 4539894458086459

// masked message delivered to subscriptions created by ReportingApplicationRole:
My credit card number is ################

For more information, see Data Protection Policy Operations, in the SNS Developer Guide.

Applying data de-identification in a use case

Consider a company where managers use an internal expense report management application where expense reports from employees can be reviewed and approved. Initially, this application depended only on an internal payment application, which in turn connected to an external payment gateway. However, this workload eventually became more complex, because the company started also paying expense reports filed by external contractors. At that point, the company built a mobile application that external contractors could use to view their approved expense reports. An important business requirement for this mobile application was that specific financial and PII data needed to be de-identified in the externally displayed expense reports. Specifically, both the credit card number used for the payment and the internal employee ID that approved the payment had to be masked.

Figure 1: Expense report processing application

Figure 1: Expense report processing application

To distribute the approved expense reports to both the payment application and the reporting application that backed the mobile application, the company used an SNS topic with a data protection policy. The policy has only one statement, which masks credit card numbers and employee IDs found in the payload. This statement applies only to the IAM role that the company used for subscribing the AWS Lambda function of the reporting application to the SNS topic. This access permission configuration enabled the Lambda function from the payment application to continue receiving the raw data from the SNS topic.

The data protection policy from the previous section addresses this use case. Thus, when a message representing an expense report is published to the SNS topic, the Lambda function in the payment application receives the message as-is, whereas the Lambda function in the reporting application receives the message with the financial and PII data masked.

Deploying the resources

You can apply a data protection policy to an SNS topic using the AWS Management Console, AWS Command Line Interface (AWS CLI), AWS SDK, or AWS CloudFormation.

To automate the provisioning of the resources and the data protection policy of the example expense management use case, we’re going to use CloudFormation templates. You have two options for deploying the resources:

Deploy using the individual CloudFormation templates in sequence

  1. Prerequisites template: This first template provisions two IAM roles with a managed policy that enables them to create SNS subscriptions and configure the subscriber Lambda functions. You will use these provisioned IAM roles in steps 3 and 4 that follow.
  2. Topic owner template: The second template provisions the SNS topic along with its access policy and data protection policy.
  3. Payment subscriber template: The third template provisions the Lambda function and the corresponding SNS subscription that comprise of the Payment application stack. When prompted, select the PaymentApplicationRole in the Permissions panel before running the template. Moreover, the CloudFormation console will require you to acknowledge that a CloudFormation transform might require access capabilities.
  4. Reporting subscriber template: The final template provisions the Lambda function and the SNS subscription that comprise of the Reporting application stack. When prompted, select the ReportingApplicationRole in the Permissions panel, before running the template. Moreover, the CloudFormation console will require, once again, that you acknowledge that a CloudFormation transform might require access capabilities.
Figure 2: Select IAM role

Figure 2: Select IAM role

Now that the application stacks have been deployed, you’re ready to start testing.

Testing the data de-identification operation

Use the following steps to test the example expense management use case.

  1. In the Amazon SNS console, select the ApprovalTopic, then choose to publish a message to it.
  2. In the SNS message body field, enter the following message payload, representing an external contractor expense report, then choose to publish this message:
    {
        "expense": {
            "currency": "USD",
            "amount": 175.99,
            "category": "Office Supplies",
            "status": "Approved",
            "created_at": "2023-10-17T20:03:44+0000",
            "updated_at": "2023-10-19T14:21:51+0000"
        },
        "payment": {
            "credit_card_network": "Visa",
            "credit_card_number": "4539894458086459"
        },
        "reviewer": {
            "employee_id": "EID-123456789-US",
            "employee_location": "Seattle, USA"
        },
        "contractor": {
            "employee_id": "CID-000012348-CA",
            "employee_location": "Vancouver, CAN"
        }
    }
    

  3. In the CloudWatch console, select the log group for the PaymentLambdaFunction, then choose to view its latest log stream. Now look for the log stream entry that shows the message payload received by the Lambda function. You will see that no data has been masked in this payload, as the payment application requires raw financial data to process the credit card transaction.
  4. Still in the CloudWatch console, select the log group for the ReportingLambdaFunction, then choose to view its latest log stream. Now look for the log stream entry that shows the message payload received by this Lambda function. You will see that the values for properties credit_card_number and employee_id have been masked, protecting the financial data from leaking into the external reporting application.
    {
        "expense": {
            "currency": "USD",
            "amount": 175.99,
            "category": "Office Supplies",
            "status": "Approved",
            "created_at": "2023-10-17T20:03:44+0000",
            "updated_at": "2023-10-19T14:21:51+0000"
        },
        "payment": {
            "credit_card_network": "Visa",
            "credit_card_number": "################"
        },
        "reviewer": {
            "employee_id": "################",
            "employee_location": "Seattle, USA"
        },
        "contractor": {
            "employee_id": "CID-000012348-CA",
            "employee_location": "Vancouver, CAN"
        }
    }
    

As shown, different subscribers received different versions of the message payload, according to their sensitive data access permissions.

Cleaning up the resources

After testing, avoid incurring usage charges by deleting the resources that you created. Open the CloudFormation console and delete the four CloudFormation stacks that you created during the walkthrough.

Conclusion

This post showed how you can use Amazon SNS message data protection to discover and protect sensitive data published to or delivered from your SNS topics. The example use case shows how to create a data protection policy that masks messages delivered to specific subscribers if the payloads contain financial or personally identifiable information.

For more details, see message data protection in the SNS Developer Guide. For information on costs, see SNS pricing.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on AWS re:Post or contact AWS Support.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.

Otavio-Ferreira-author

Otavio Ferreira

Otavio is the GM for Amazon SNS, and has been leading the service since 2016, responsible for software engineering, product management, technical program management, and technical operations. Otavio has spoken at AWS conferences—AWS re:Invent and AWS Summit—and written a number of articles for the AWS Compute and AWS Security blogs.

How to prevent SMS Pumping when using Amazon Pinpoint or SNS

Post Syndicated from Akshada Umesh Lalaye original https://aws.amazon.com/blogs/messaging-and-targeting/how-to-prevent-sms-pumping-when-using-amazon-pinpoint-or-sns/

SMS fraud is, unfortunately, a common issue that all senders of SMS encounter as they adopt SMS as a communication channel. This post defines the most common types of fraud and provides concrete guidance on how to mitigate or eliminate each of them.

Introduction to SMS Pumping:

SMS Pumping, also known as an SMS Flood attack, or Artificially Inflated Traffic (AIT), occurs when fraudsters exploit a phone number input field to acquire a one-time passcode (OTP), an app download link, or any other content via SMS. In cases where these input forms lack sufficient security measures, attackers can artificially increase the volume of SMS traffic, thereby exploiting vulnerabilities in your application. The perpetrators dispatch SMS messages to a selection of numbers under the jurisdiction of a particular mobile network operator (MNO), ultimately receiving a portion of the resulting revenue. It is essential to understand how to detect these attacks and prevent them.

Common Evidence of SMS Pumping:

  • Dramatic Decrease in Conversion Rates: A common SMS use case is for identity verification through the use of One Time Passwords (OTP) but this could also be seen in other types of use cases where a clear and consistent conversion rate is seen. A drop in a normally stable conversion rate may be caused by an increase in volume that will never convert and can indicate an issue that requires investigation. Setting up an alert for anomalies in conversion rates is always a good practice.
  • SMS Requests or Deliveries from Unknown Countries: If your application normally sends SMS to a defined set of countries and you begin to receive requests for a different country, then then this should be investigated.
  • Spike in Outgoing Messages: A significant and sudden increase in outgoing messages could indicate an issue that requires investigation.
  • Spike in Messages Sent to a Block of Adjacent Numbers: Fraudsters often deploy bots and programmatically loop through numbers in a sequence. You will probably notice an increase in messages to a group of nearby numbers frequently for example, +11111111110, +11111111111

How to Identify and Prevent SMS Pumping Attacks:

Now that we understand the common signs of SMS pumping, lets discuss how to use AWS Services to identify, confirm the fraud and how to place measures in place to prevent it in the first place.

Identify:

Delivery Statistics (UTC)

Delivery Statistics (UTC)

If you are using Amazon Pinpoint, you can use transactional messaging under analytics section to understand the SMS patterns

Transactional Messaging Charts

Transactional Messaging Charts

  • Spikes in Messages Sent to a Block of Adjacent Numbers: If you are using SNS you can use CloudWatch logs to analyse the destination numbers.

You can use CloudWatch Insights query on below log groups

sns/<region>/<Accountnumber>/DirectPublishToPhoneNumber
sns/<region>/<Accountnumber>/DirectPublishToPhoneNumber/failure

The below query will print all the logs that have the destination number like +11111111111
fields @timestamp, @message, @logStream, @log
| filter delivery.destination like '+11111111111'
| limit 20

If you are using Amazon Pinpoint, you can enable event stream to analyse destination numbers.

If you have deployed Digital User Engagement Events Database Solution You can use the below sample Amazon Athena query which displays entries that have the destination number like +11111111111

SELECT * FROM "due_eventdb"."sms_success" where destination_phone_number like '%11111111111%'
SELECT * FROM "due_eventdb"."sms_failure" where destination_phone_number like '%11111111111%'

How to Prevent SMS Pumping: 

      • Example: If you expect only users from India to sign up in your application, you can include rules such as “\+91[0-9]{10}”, which allows only Indian numbers as input.
      • Note: SNS and Pinpoint APIs are not natively integrated with WAF. However, you can connect your application to an Amazon API Gateway with which you can integrate with WAF.
      • How to Create a Regex Pattern Set with WAF – The below Regex Pattern set will allow sending messages to Australia (+61) and India (+91) destination phone numbers
          1. Sign in to the AWS Management Console and navigate to AWS WAF console
          2. In the navigation pane, choose Regex pattern sets and then Create regex pattern set.
          3. Enter a name and description for the regex pattern set. You’ll use these to identify it when you want to use the set. For example, Allowed_SMS_Countries
          4. Select the Region where you want to store the regex pattern set
          5. In the Regular expressions text box, enter one regex pattern per line
          6. Review the settings for the regex pattern set, and choose Create regex pattern set
Regex pattern set details

Regex pattern set details

      • Create a Web ACL with above Regex Pattern Set
          1. Sign in to the AWS Management Console and navigate to AWS WAF console
          2. In the navigation pane, choose Web ACLs and then Create web ACL
          3. Enter a Name, Description and CloudWatch metric name for Web ACL details
          4. Select Resource type as Regional resources
          5. Click Next

            Web ACL details

            Web ACL details

          6. Click on Add Rules > Add my own rules and rule groups
          7. Enter Rule name and select Regular rule

            Web ACL Rule Builder

            Web ACL Rule Builder

          8. Select Inspect > Body, Content type as JSON, JSON match scope as Values, Content to inspect as Full JSON content
          9. Select Match type as Matches pattern from regex pattern set and select the Regex pattern set as “Allowed_SMS_Countries” created above
          10. Select Action as Allow
          11. Click Add Rule  

            Web ACL Rule builder statement

            Web ACL Rule builder statement

          12. Select Block for Default web ACL action for requests that don’t match any rules

            Web ACL Rules

            Web ACL Rules

          13. Set rule priority and Click Next

            Web ACL Rule priority

            Web ACL Rule priority

          14. Configure metrics and Click Next

            Web ACL metrics

            Web ACL metrics

          15. Review and Click Create web ACL

For more information, please refer to WebACL

  • Rate Limit Requests
    • AWS WAF provides an option to rate limit per originating IP. You can define the maximum number of requests allowed in a five-minute period that satisfy the criteria you provide, before limiting the requests using the rule action setting
  • CAPTCHA
    • Implement CAPTCHA in your application request process to protect your application against common bot traffic
  • Turn off “Shared Routes”
  • Exponential Delay Verification Retries
    • Implement a delay between multiple messages to the same phone number. This doesn’t completely eliminate but will help slow down the attack
  • Set CloudWatch Alarm
  • Validate Phone Numbers – You can use the Pinpoint Phone number validate API to check the values for CountryCodeIso2, CountryCodeNumeric, and PhoneType prior to sending SMS and then only send SMS to countries that match your criteria
    Sample API Response:

{
"NumberValidateResponse": {
"Carrier": "ExampleCorp Mobile",
"City": "Seattle",
"CleansedPhoneNumberE164": "+12065550142",
"CleansedPhoneNumberNational": "2065550142",
"Country": "United States",
"CountryCodeIso2": "US",
"CountryCodeNumeric": "1",
"OriginalPhoneNumber": "+12065550142",
"PhoneType": "MOBILE",
"PhoneTypeCode": 0,
"Timezone": "America/Los_Angeles",
"ZipCode": "98101"
}
}

Conclusion:

This post covers the basics of SMS pumping attacks, the different mechanisms that can be used to detect them, and some potential ways to solve for or mitigate them using services and features like Pinpoint Validate API and WAF.

Further Reading:
Review the documentation of WAF with API gateway
here
Review the documentation of Phone number validate
here
Review the Web Access Control lists
here


Resources:
Amazon Pinpoint –
https://aws.amazon.com/pinpoint/
Amazon API Gateway –
https://aws.amazon.com/api-gateway/
Amazon Athena –
https://aws.amazon.com/athena/

IAM Roles Anywhere with an external certificate authority

Post Syndicated from Cody Penta original https://aws.amazon.com/blogs/security/iam-roles-anywhere-with-an-external-certificate-authority/

AWS Identity and Access Management Roles Anywhere allows you to use temporary Amazon Web Services (AWS) credentials outside of AWS by using X.509 Certificates issued by your certificate authority (CA). Faraz Angabini goes deep into using IAM Roles Anywhere in his blog post Extend AWS IAM roles to workloads outside of AWS with IAM Roles Anywhere. In this blog post, I take a step back from his post and first define what public key infrastructure (PKI) is and help you set one up for use for IAM Roles Anywhere.

I focus on setting up local PKI for testing purposes by building a basic, minimal certificate authority using openssl. I chose openssl as it’s a standard industry tool for cryptography and is often installed by default on many operating systems. However, you can achieve similar results in a simpler manner using open source tools such as cfssl. In this blog post, we create a local PKI for non-production use cases only for the sake of brevity and to focus more on understanding the core fundamentals. As I go along, I’ll point out what I left out and where to find more information.

Overview

The overall flow of this blog is as follows, there’s some new terminology, so please use this as a map to refer to as you read along to understand the flow. If you’re taking cornell notes, now would be the right time to write key words you see below such as key, certificate, end-entity certificate, certificate authority, CA, trust, IAM Roles Anywhere, and others that pop out to you.

  1. Explain the concepts of keys and certificates and their uses.
  2. Using what you learn about keys and certificates, create a CA.
  3. Import your certificate authority into IAM Roles Anywhere and establish trust between your certificate authority and IAM Roles Anywhere.
  4. Create an end-entity certificate.
  5. Exchange your end-entity certificate for IAM credentials using IAM Roles Anywhere.

Background

IAM Roles Anywhere is compatible with existing PKIs, and for demonstration purposes, you’ll create local infrastructure using openssl to get a deep understanding of the terminology and concepts. Existing PKIs such as AWS Certificate Manager (ACM) and third-party certificate authority services often abstract and simplify this process. With that being said, you have to start somewhere, so let’s start with a key.

What exactly is a key? The National Institute of Standards and Technology (NIST) defines a key as “a parameter used in conjunction with a cryptographic algorithm that determines the specific operation of that algorithm,” which is a formal way of saying for anything you would put inside the key parameter in a function like encrypt(key, data), decrypt(key, data), or sign(key, data). The definition cleverly avoids defining the key by its structure—such as, “It’s a sequence of 256 truly random bits” — as that’s not always the case. For example, in asymmetric encryption you have two keys. One key is private and should not, under any circumstances, be shared outside of your control; while another key is public and can be safely shared with the outside world. To illustrate this, let’s look at actual commands to generate keys:

openssl genpkey -out private.key \
    -algorithm RSA \
    -pkeyopt rsa_keygen_bits:2048 # 2048 minimum key size for RSA, later we use 4096

NOTE: The key is printed in PKCS#8 format, which is a file format for the private key along with some metadata

You can inspect this key with:

cat private.key
-----BEGIN PRIVATE KEY-----
MIIEvgIBADANBgkqhkiG9w0BAQEFAASCBKgwggSkAgEAAoIBAQC/BWpcJqlVDJkC
wr+qrwEgNPSpXM2iSQQAfjS81pll4I5yp//7lm1UqKeBTbaYp9rVec1uzKQrw3xt
...36 lines removed for brevity
mx2sovZyFB7Xe4/99TGLQuHTtgLYYVEN/iFtvsbjPjR7X+R76GWPLdUFdRes0gPo
dlsfnsVKVkUUJKZy0Y2nOrwb2gNSUd/NjcgV9XHEW4y+Sclk/EkdAML1d3aGM0VQ
AaLL8xb75To0VqSQPW12URJM
-----END PRIVATE KEY-----

The public key is embedded inside the private key and you can even pull the public part from the private key.

openssl pkey -in private.key -pubout -out public.key

And like the private key, you can inspect it:

cat public.key
-----BEGIN PUBLIC KEY-----
MIIBIjANBgkqhkiG9w0BAQEFAAOCAQ8AMIIBCgKCAQEAvwVqXCapVQyZAsK/qq8B
IDT0qVzNokkEAH40vNaZZeCOcqf/+5ZtVKingU22mKfa1XnNbsykK8N8bSY9J4r5
f9DVDN8YmRh1+YEYB8pkFTjZBuz158F9GVRK9r/6Lr2Ft0RAinGiN4LoO+V++Ofk
LITgB0rqMk1UH8XyUJwHkS5btr5M7v7zudiQiUDW4vRpWTJ/I4mb9Y2brMfMxJpg
nJ0ni1pm8Yz8zcVjFklvkdtQD+wx4DXf4/7o2EDBNPc1gW+9gIpCI1h5TMwXWURH
lY9cM03SqKwj6SzHxRdOjcMC1Zie3+8OKr1HYpMT0AIM85T3q1iUif8s0TQ3Mk9o
jQIDAQAB
-----END PUBLIC KEY-----

While you must keep your private key a secret, you can openly share your public key. You can even copy the key multiple times and rename each copy to designate an individual whom you would hand the public key out to.

cp public.key alice-public.key
cp public.key bob-public.key

ls
alice-public.key bob-public.key  private.key  public.key

Now here’s the most critical question that I cannot stress enough:

Who owns these keys?

Does the server that generated this private key own it? Do I, as the author of this blog, own it? Does Amazon, as the company, own this private key?

What about the public keys? Who exactly is Alice (alice-public.key)? Who is Bob (bob-public.key)? How are Bob and Alice different if they have the same public key? These are all rhetorical questions you should be asking yourself when working with cryptographic keys. It helps answer who is responsible for this key and ultimately any data encrypted/unencrypted with that key.

At its core, public key infrastructure (PKI) can be explained as assigning an identity to someone or something and using cryptographic keys to ensure that identity can be verified. In the case of internal PKIs, the someone or something is often a hierarchy of assets belonging to your company. For example, a flow could be:

  • Your company
    • Your company’s business unit
      • business unit servers
      • business unit load balancers
      • business unit clients
    • Another business unit

Step 1: Set up a root certificate authority

You need to start somewhere, right? To get a publicly trusted identity, you often need to go through a certificate management service like AWS Certificate Manager (ACM) or a third-party vendor. These vendors go through several audits with operating system providers to have their identity trusted on the operating system itself. For example, on MacOS, you can open the Keychain Access app, go to System Roots, and look at the Certificates tab to see identities that are managed on your behalf.

In this use case with IAM Roles Anywhere, you don’t have to worry about interacting with operating system providers, because you’re creating your own internal PKI—your own internal identity. You do this by creating a certificate authority.

But hold on now, what exactly is a certificate authority? For that matter, what is a certificate?

A certificate is a wrapper around a public key that assigns metadata to an entity. Remember how you can copy the public key and just rename it to alice-public.key? You’ll need a little more metadata than that but the concept is the same. Examples of metadata include “Who are you?” “Who gave you this key?” “When should this key expire?” “Here is what you’re allowed to use this key for,” and various other attributes. As you can imagine, you don’t want just anybody to provide you this type of metadata. You want trusted authorities to assign or validate that metadata for you, and so the term certificate authorities. Certificate authorities also sign these certificates using a digital signing algorithm such as RSA so that consumers of these certificates can verify that the metadata inside hasn’t been tampered with.

You want to be the certificate authority within your own internal network. So how do you go about doing that? Turns out, you’ve already completed the most critical step: creating a private key. By creating a cryptographically strong, random private key, you can assert that whoever owns this private key, represents our company. You can do so because it’s highly improbable that anyone could guess or brute-force this key. However, that means every mechanism you use to protect this private key is critical.

Remember though, you need an identity, and simply naming your private key anycompany.private.key and public key usecase.public.key isn’t ideal. It’s not ideal because you need a lot more metadata than a file name. You need metadata like you would have in the earlier certificate example. You need a certificate that represents your certificate authority, a sort of ID for your root certificate. To facilitate that, there’s a field in certificates called IsCA that’s either true or false. Meaning whether or not a certificate is simply a certificate or a certificate authority is determined by a flag inside the certificate. We’ll start by writing out an openssl configuration file that is used throughout multiple certificate management commands.

NOTE: What’s the difference between a root certificate and a root certificate authority? You can think of a root certificate authority as a person who stamps other certificates. This person themselves needs an ID card. That ID card is the root certificate.

# NOTE: Examples derived from Ivans Ristic's Github
# https://github.com/ivanr/bulletproof-tls
# You may also use `man ca` at the CLI for more examples

# Basic Info about the CA
[default]
name                    = root-ca
domain_suffix           = example.com
default_ca              = ca_default
name_opt                = utf8,esc_ctrl,multiline,lname,align

[ca_dn]
countryName             = "US"
organizationName        = "Any Company Corp"
commonName              = "internal.anycompany.com"

# How the CA Should operate
[ca_default]
home                    = root-ca
database                = $home/db/index
serial                  = $home/db/serial
certificate             = $home/$name.crt
private_key             = $home/private/$name.key
RANDFILE                = $home/private/random
new_certs_dir           = $home/certs
unique_subject          = no
copy_extensions         = none
default_days            = 3650
default_md              = sha256
policy                  = policy_c_o_match

[policy_c_o_match]
countryName             = match
stateOrProvinceName     = optional
organizationName        = match
organizationalUnitName  = optional
commonName              = supplied
emailAddress            = optional

# Configuration for `req` command
[req]
default_bits            = 4096
encrypt_key             = yes
default_md              = sha256
utf8                    = yes
string_mask             = utf8only
prompt                  = no
distinguished_name      = ca_dn
req_extensions          = ca_ext

[ca_ext]
basicConstraints        = critical,CA:true
keyUsage                = critical,keyCertSign
subjectKeyIdentifier    = hash
# create-root-ca.sh
mkdir -p root-ca/certs   # New Certificates issued are stored here
mkdir -p root-ca/db      # Openssl managed database
mkdir -p root-ca/private # Private key dir for the CA

chmod 700 root-ca/private
touch root-ca/db/index

# Give our root-ca a unique identifier
openssl rand -hex 16 > root-ca/db/serial

# Create the certificate signing request
openssl req -new \
  -config root-ca.conf \
  -out root-ca.csr \
  -keyout root-ca/private/root-ca.key

# Sign our request
openssl ca -selfsign \
  -config root-ca.conf \
  -in root-ca.csr \
  -out root-ca.crt \
  -extensions ca_ext

But there are a few things I have to point out:

  • Most certificates start their lives as a certificate signing request (CSR). They contain most of the data an actual certificate does and only become a certificate when signed either by the same entity that created it (self-signed certificate) or by another entity (external certificate authority). This is why you see openssl req followed by openssl ca -selfsign.
  • Everything under root-ca/ must now be protected, especially anything generated under root-ca/private/.
  • I skipped quite a few steps for the sake of brevity, including creating a subordinate certificate authority and keeping the root certificate authority offline, as well as adding a certificate revocation list and Online Certificate Status Protocol (OSCP) capabilities. These can be their own book and I would instead recommend reading Bulletproof TLS and PKI by Ivan Ristic. In this post, I include the bare minimum to import a certificate and get started with IAM Roles Anywhere. As a side note, if you’re importing a certificate from a certificate authority managed outside of AWS, it should come with these capabilities as well.

It’s good practice to inspect the actual root-ca.crt that was returned to you.

openssl x509 -in root-ca.crt -text -noout

Note: If you want to inspect and compare the root-ca.crt with the certificate signing request root-ca.csr, you can use openssl req -text -noout -verify -in root-ca.csr.

What you look for in the following output are that fields such as Subject, Public-Key Algorithm, and the CA:TRUE flag are set and correspond to the configuration you passed in earlier. Additional things to look for are Issuer (yourself since it’s self-signed), and Key Usage (what the public key included in the certificate is allowed to be used for).

Certificate:
    Data:
        Version: 3 (0x2)
        Serial Number:
            95:77:30:1a:1b:bc:ce:70:f3:e7:ff:1c:12:d2:01:c7
        Signature Algorithm: sha256WithRSAEncryption
        Issuer: C = US, O = Any Company Corp, CN = internal.anycompany.com
        Validity
            Not Before: Jul 5 20:52:33 2023 GMT
            Not After : Jul 2 20:52:33 2033 GMT
        Subject: C = US, O = Any Company Corp, CN = internal.anycompany.com
        Subject Public Key Info:
            Public Key Algorithm: rsaEncryption
                Public-Key: (4096 bit)
                ...
        X509v3 extensions:
            X509v3 Basic Constraints: critical
                CA:TRUE
            X509v3 Key Usage: critical
                Certificate Sign
            ...
    Signature Algorithm: sha256WithRSAEncryption
    Signature Value:
        ...

Now why is this certificate especially important? This is your root certificate. When you’re asked “Does this certificate belong to your company?” this is the certificate that you must use in order to prove that it belongs to your company, including any certificates derived from this root certificate (remember, you can have a hierarchy) and also end-entity certificates (shown later). All certificates derived from this root certificate are cryptographically linked to it through a digital signing algorithm that combines hashing and encryption to sign the certificate (the example above uses sha256WithRSAEncryption).

With your root CA successfully set up, it’s time to integrate it with IAM Roles Anywhere.

Step 2: Set up IAM Roles Anywhere

Step 1: Set up a root certificate authority (root CA) was a prerequisite for using IAM Roles Anywhere. Remember, you set up all this infrastructure to eventually use it. In step 2, you start going through how to effectively use the root CA you set up to issue AWS credentials outside of the AWS ecosystem.

But before you do that, you must bind the IAM Roles Anywhere service to your private certificate authority (private CA). You do this by setting up a trust between the two. When you set up trust between two things, you’re essentially saying “I don’t have the information to verify this is a valid request, so I’m going to trust that the downstream component (in this case, your private CA) knows this information.” Another way of saying it is “if the private CA says it’s good, then it’s a valid request”. You can set up this trust with your newly created root CA by copying the encoded section of your root-ca.crt in the IAM Roles Anywhere console.

To set up the trust

  1. Go the the IAM Roles Anywhere console.
  2. Under External certificate bundle, paste the encoded section of your root-ca.crt.
  3. Submit the form.
tail -n 31 root-ca.crt
-----BEGIN CERTIFICATE-----
MIIFXTCCA0WgAwIBAgIRAJV3MBobvM5w8+f/HBLSAccwDQYJKoZIhvcNAQELBQAw
SDELMAkGA1UEBhMCVVMxGDAWBgNVBAoMD015IENvbXBhbnkgQ29ycDEfMB0GA1UE
...lines removed for brevitity
iCmHNvGCkBMBo08PLPuynuY69IJCdbjv6iudspBQDdu9aYNPF8BWR3dsTjPpsbOw
ef33wuHiCj4nH96wCrSmPoIUfc4UEp7eZiS0A9xHw8TkT5Uzyq9ZThSaTqBZfojD
zGtnpprPTg/lCHDmoTbGmrOp9ByWU3qQUK7ZtzxSjhjT
-----END CERTIFICATE-----
Figure 1: Use the console to set up a trust between IAM Roles Anywhere and the private CA

Figure 1: Use the console to set up a trust between IAM Roles Anywhere and the private CA

What you just set up is a trust anchor, which is a representation of your certificate authority inside of IAM Roles Anywhere. With this trust anchor in place, you can start tying in IAM roles to your authentication. Let’s start with something simple but practical, imagine an on-premises virtual machine (VM) that needs to have read access to Amazon Simple Storage Service (Amazon S3). Not only that, but it must have read only access to a specific folder in Amazon S3 and only that folder.

The first thing you need to do is create an IAM role that trusts IAM Roles Anywhere. But you need to be more specific than that. You need to create a role that trusts IAM Roles Anywhere only when the certificate presented to IAM Roles Anywhere contains the common name MyOnpremVM. If this is unclear, that’s okay, after you have all of the prerequisites set up, you’ll walk through the entire process step by step. The following is the trust section in an IAM policy that can be created in the IAM console.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Principal": {
                "Service": [
                    "rolesanywhere.amazonaws.com"
                ]
            },
            "Action": [
              "sts:AssumeRole",
              "sts:TagSession",
              "sts:SetSourceIdentity"
            ],
            "Condition": {
              "ArnEquals": {
                "aws:SourceArn": [
                  "arn:aws:rolesanywhere:us-east-1:111222333444:trust-anchor/d5302884-5212-4f8d-9b17-24be63a5ae85"
                ]
              },
              "StringEquals": {
                "aws:PrincipalTag/x509Subject/CN": "MyOnpremVM"
              }
            }
        }
    ]
}

The second thing you need to create is the actual Amazon S3 permissions:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "ListObjectsInBucket",
            "Effect": "Allow",
            "Action": "s3:ListBucket",
            "Resource": "arn:aws:s3:::DOC-EXAMPLE-BUCKET",
            "Condition": {
                "StringLike": {
                    "s3:prefix": [
                        "MyOnPremVM/*"
                    ]
                }
            }
        },
        {
            "Effect": "Allow",
            "Action": "s3:*",
            "Resource": [
                "arn:aws:s3:::DOC-EXAMPLE-BUCKET/MyOnPremVM",
                "arn:aws:s3:::DOC-EXAMPLE-BUCKET/MyOnPremVM/*"
            ]
        }
    ]
}

Note: There are other certificate fields you might want to key off as well. See Trust policy in the documentation for more examples.

The last thing to do before moving on is to tie a set of roles to a profile. You can think of it as a container of multiple possible roles with the ability to further restrict them using session policies. Note that you use the role ARN for the S3 role you just created.

aws rolesanywhere create-profile --name DefaultProfile --role-arns arn:aws:iam::111222333444:role/RolesAnywhereS3Role
{
    "profile": {
        "createdAt": "2023-05-01T22:29:36.088864+00:00",
        "createdBy": "arn:aws:sts::111222333444:assumed-role/<role-name>",
        "durationSeconds": 3600,
        "enabled": false,
        "name": "DefaultProfile",
        "profileArn": "arn:aws:rolesanywhere:us-east-1:111222333444:profile/2845dde5-9c82-480d-a6a6-f61240e42d4a",
        "profileId": "2845dde5-9c82-480d-a6a6-f61240e42d4a",
        "roleArns": [
            "arn:aws:iam::111222333444:role/RolesAnywhereS3"
        ],
        "updatedAt": "2023-05-01T22:29:36.088864+00:00"
    }
}

Profiles are created disabled by default, you can enable them later as needed. You could also enable a profile on creation by using the --enabled flag, but I want to highlight the ability to create it as disabled and then enabled it later for awareness. This becomes relevant in cases when you need to disable access, such as during a security event. Use the following command to enable the profile after creating it:

aws rolesanywhere enable-profile --profile-id 2845dde5-9c82-480d-a6a6-f61240e42d4a

Now that all your infrastructure is in place, it’s time to provision an end-entity certificate and assume the role you created earlier.

Creating an end-entity certificate

The first thing you must do is obtain an end-entity certificate. This is called end-entity because a certificate can have an entire chain of certificates that are linked together. The end-entity certificate is at the end of the chain, which commonly represents individual entities, and so the term end-entity certificate.

Similar to how you set up your root certificate, it’s mostly a two-step process. You first create a certificate signing request and then ask someone to sign it (or sign it yourself). You can create a certificate signing request for your on-premises VM with:

# Make your private key specific to your client machine
openssl genpkey -out client.key \
  -algorithm RSA \
  -pkeyopt rsa_keygen_bits:2048
  
# Using your newly generated private key make a certificate signing request
openssl req -new -key client.key -out client.csr

# You'll be presented an interactive session to enter details for the CSR
You are about to be asked to enter information that will be incorporated
into your certificate request.
What you are about to enter is what is called a Distinguished Name or a DN.
There are quite a few fields but you can leave some blank
For some fields there will be a default value,
If you enter '.', the field will be left blank.
-----
Country Name (2 letter code) [XX]:US
State or Province Name (full name) []:WA
Locality Name (eg, city) [Default City]:Seattle
Organization Name (eg, company) [Default Company Ltd]:Any Company Corp
Organizational Unit Name (eg, section) []:Sales
Common Name (eg, your name or your server's hostname) []:MyOnpremVM
Email Address []:

Please enter the following 'extra' attributes
to be sent with your certificate request
A challenge password []:
An optional company name []:

As always, let’s inspect the certificate we made.

openssl req -text -noout -verify -in client.csr

The client name (common name (CN) in the certificate) is what’s most important here, after all this is how we uniquely identify this specific VM.

Certificate Request:
    Data:
        Version: 0 (0x0)
        Subject: C=US, ST=WA, L=Seattle, O=Any Company Corp, OU=Sales, CN=MyOnpremVM
        Subject Public Key Info:
            Public Key Algorithm: rsaEncryption
                Public-Key: (4096 bit)
                Modulus:
                    00:ae:d0:ab:2d:20:2d:44:b5:36:ad:de:dd:23:ac:
                    ...32 lines removed for brevity
                    89:98:ef:b6:86:bf:c2:16:08:55:2d:5e:45:af:24:
                    17:45:cb
                Exponent: 65537 (0x10001)
        Attributes:
            a0:00
    Signature Algorithm: sha256WithRSAEncryption
         08:b4:86:66:14:1f:03:12:0b:36:15:42:2b:ae:56:7b:ba:99:
         ...27 lines removed for brevity
         00:bb:06:88:6b:c7:c2:53

Signing an end-entity certificate

Now that you have your certificate signing request, the certificate must be signed. Let’s have your private root CA that you created in Step 1 sign this certificate.

NOTE: You might have to move your root-ca.crt file into whatever $home is inside of your root-ca.conf file before running the following command.

openssl ca \
  -config root-ca.conf \
  -in client.csr \
  -out client.crt \
  -extensions client_ext

You’ll be asked to manually verify the certificate you’re about to sign. The key things you need to pay attention to for the purposes of IAM Roles Anywhere are:

  • Common Name because that’s how permissions and to what S3 bucket are decided.
  • Key usage specifies Digital Signature, and basic constraints specify CA:FALSE. Both are required to work with IAM Roles Anywhere.
Certificate:
    Data:
        Version: 1 (0x0)
        Serial Number:
            95:77:30:1a:1b:bc:ce:70:f3:e7:ff:1c:12:d2:01:c8
        Issuer:
            countryName               = US
            organizationName          = Any Company Corp
            commonName                = internal.anycompany.com
        Validity
            Not Before: Jul  6 14:46:49 2023 GMT
            Not After : Jul  3 14:46:49 2033 GMT
        Subject:
            countryName               = US
            stateOrProvinceName       = WA
            organizationName          = Any Company Corp
            organizationalUnitName    = Sales
            commonName = MyOnpremVM
        Subject Public Key Info:
            Public Key Algorithm: rsaEncryption
                Public-Key: (2048 bit)
                ...
        X509v3 extensions:
            ...
            X509v3 Basic Constraints: critical
                CA:FALSE
            X509v3 Key Usage: critical
                Digital Signature
            ...
Certificate is to be certified until Jul  3 14:46:49 2033 GMT (3650 days)
Sign the certificate? [y/n]:

After verification, you can commit the certificate to the local database and move on to the next step.

Swapping an end-entity certificate for AWS credentials

Now it’s time for the moment of truth. To review, you have:

  1. Created a local CA
  2. Uploaded the CA certificate into IAM Roles Anywhere and created a trust anchor
  3. Created an IAM role that trusts IAM Roles Anywhere, which in turn trusts your CA certificate
  4. Created an end-entity certificate for a specific server that has been signed by your CA

It’s time to swap this certificate for IAM credentials.

The API you call to swap credentials is CreateSession for IAM Roles Anywhere. This API serves as a wrapper around STS AssumeRole but requires that you pass in certificate information first. You, as the end user, don’t directly call this API. Instead, you use the IAM Roles Anywhere credential helper.

You can get the binary for this helper using the following example command (for Linux).

NOTE: The URL in the example uses version 1.0.4 of the credential helper as there isn’t a latest path. Verify that you’re getting the latest version using the table found inside of IAM roles anywhere documentation.

curl https://rolesanywhere.amazonaws.com/releases/1.0.4/X86_64/Linux/aws_signing_helper --output aws_signing_helper

Then use the credential helper tool to successfully swap for AWS credentials.

NOTE: You pass in the private key, but the private key doesn’t leave the host, it’s used to sign the request to CreateSession. See the signing process to learn more. The signing process is also why you use the credentials helper instead of making a call directly to CreateSession.

./aws_signing_helper credential-process \
  --certificate client.crt \
  --private-key client.key \
  --role-arn arn:aws:iam::111222333444:role/RolesanywhereS3Role \
  --trust-anchor-arn arn:aws:rolesanywhere:us-east-1:111222333444:trust-anchor/d5302884-5212-4f8d-9b17-24be63a5ae85
  --profile-arn arn:aws:rolesanywhere:us-east-1:111222333444:profile/e341077c-4ee6-48e8-8d05-d900eb26b367
{
 "Version":1,
 "AccessKeyId":"ASIAEXAMPLEID",
 "SecretAccessKey":"wWPZTXfKdp8UF6HDpfbTEboEXAMPLESECRETKEY",
 "SessionToken":"IQoJb3JpZ2luX2VjEK///EXAMPLESESSIONTOKEN",
 "Expiration":"2023-05-01T23:37:10Z"
}

You can write the command you just ran into your AWS Config file instead of manually parsing the JSON response into environment variables, or run the serve command to set up a local credential-serving endpoint that’s compatible with the AWS SDK and AWS Command Line Interface (AWS CLI).

./aws_signing_helper serve \
  --certificate client.crt \
  --private-key client.key \
  --role-arn arn:aws:iam::111222333444:role/RolesanywhereS3Role \
  --trust-anchor-arn arn:aws:rolesanywhere:us-east-1:111222333444:trust-anchor/d5302884-5212-4f8d-9b17-24be63a5ae85 \
  --profile-arn arn:aws:rolesanywhere:us-east-1:111222333444:profile/e341077c-4ee6-48e8-8d05-d900eb26b367 \
  & # Start the process in the background

Then export the AWS_EC2_METADATA_SERVICE_ENDPOINT environment variable to point the AWS SDKs and AWS CLI to a local mock EC2 metadata endpoint instead of the endpoint normally found inside EC2 instances.

export AWS_EC2_METADATA_SERVICE_ENDPOINT=http://127.0.0.1:9911/

Then finally, confirm that you assumed the right role with:

aws sts get-caller-identity
{
    "UserId": "AROARIEKBWA5HJMA7JDOJ:00bd58e6934d37bf2c3e19afb4c8cac58c",
    "Account": "111222333444",
    "Arn": "arn:aws:sts::111222333444:assumed-role/RolesAnywhereS3/00bd58e6934d37bf2c3e19afb4c8cac58c"
}

And from here, you can use the AWS CLI or SDKs to make calls into AWS with the permissions you set up. For example, test your permissions by writing an object to Amazon S3 at a location you should be able to write to and a location you shouldn’t be.

# Failure case
aws s3 cp client.crt s3://DOC-EXAMPLE-BUCKET/notme/client.crt
upload failed: ./client.crt to s3://DOC-EXAMPLE-BUCKET/notme/client.crt An error occurred (AccessDenied) when calling the PutObject operation: Access Denied
# Passing Case
aws s3 cp client.crt s3://DOC-EXAMPLE-BUCKET/MyOnPremVM/client.crt
upload: ./client.crt to s3://DOC-EXAMPLE-BUCKET/MyOnPremVM/client.crt

Conclusion

To summarize, I started off this blog post discussing core concepts related to public key infrastructure. I talked about the purpose of keys (being improbable to guess) and certificates (tying an identity to a key, among other important concepts such as digital signing). I then discussed and showed you how to create a local certificate authority (CA), then use that CA to vend out end-entity certificates. Finally, you learned how to establish a trust relationship between your CA and IAM Roles Anywhere to allow IAM Roles Anywhere to verify end-entity certificates and exchange them with AWS credentials.

I encourage you to explore any other openssl commands and scenarios you can imagine. For example, how would you use this information to handle two different fleets of VMs, each with their own unique set of permissions? Another avenue to explore would be using cfssl instead of openssl to create a CA or using a provider such as AWS Private Certificate Authority. You can use an AWS account to try AWS Private Certificate Authority with a 30-day trial. See AWS Private CA Pricing to learn more.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Cody Penta

Cody Penta

Cody Penta is a Solutions Architect at Amazon Web Services and is based out of Charlotte, NC. He has a focus in security and CDK, and enjoys solving the really difficult problems in the technology world. Off the clock, he loves relaxing in the mountains, coding personal projects, and gaming.

Maintaining a local copy of your data in AWS Local Zones

Post Syndicated from Macey Neff original https://aws.amazon.com/blogs/compute/maintaining-a-local-copy-of-your-data-in-aws-local-zones/

This post is written by Leonardo Solano, Senior Hybrid Cloud SA and Obed Gutierrez, Solutions Architect, Enterprise.

This post covers data replication strategies to back up your data into AWS Local Zones. These strategies include database replication, file based and object storage replication, and partner solutions for Amazon Elastic Compute Cloud (Amazon EC2).

Customers running workloads in AWS Regions are likely to require a copy of their data in their operational location for either their backup strategy or data residency requirements. To help with these requirements, you can use Local Zones.

Local Zones is an AWS infrastructure deployment that places compute, storage, database, and other select AWS services close to large population and industry centers. With Local Zones, customers can build and deploy workloads to comply with state and local data residency requirements in sectors such as healthcare, financial services, gaming, and government.

Solution overview

This post assumes the database source is Amazon Relational Database Service (Amazon RDS). To backup an Amazon RDS database to Local Zones, there are three options:

  1. AWS Database Migration Service (AWS DMS)
  2. AWS DataSync
  3. Backup to Amazon Simple Storage Service (Amazon S3)

. Amazon RDS replication to Local Zones with AWS DMS

Figure 1. Amazon RDS replication to Local Zones with AWS DMS

To replicate data, AWS DMS needs a source and a target database. The source database should be your existing Amazon RDS database. The target database is placed in an EC2 instance in the Local Zone. A replication job is created in AWS DMS, which maintains the source and target databases in sync. The replicated database in the Local Zone can be accessed through a VPN. Your database administrator can directly connect to the database engine with your preferred tool.

With this architecture, you can maintain a locally accessible copy of your databases, allowing you to comply with regulatory requirements.

Prerequisites

The following prerequisites are required before continuing:

  • An AWS Account with Administrator permissions;
  • Installation of the latest version of AWS Command Line Interface (AWS CLI v2);
  • An Amazon RDS database.

Walkthrough

1. Enabling Local Zones

First, you must enable Local Zones. Make sure that the intended Local Zone is parented to the AWS Region where the environment is running. Edit the commands to match your parameters, group-name makes reference to your local zone group and region to the region identifier to use.

aws ec2 modify-availability-zone-group \
  --region us-east-1 \
  --group-name us-east-1-qro-1\
  --opt-in-status opted-in

If you have an error when calling the ModifyAvailabilityZoneGroup operation, you must sign up for the Local Zone.

After enabling the Local Zone, you must extend the VPC to the Local Zone by creating a subnet in the Local Zone:

aws ec2 create-subnet \
  --region us-east-1 \
  --availability-zone us-east-1-qro-1a \
  --vpc-id vpc-02a3eb6585example \
  --cidr-block my-subnet-cidr

If you need a step-by-step guide, refer to Getting started with AWS Local Zones. Enabling Local Zones is free of charge. Only deployed services in the Local Zone incur billing.

2. Set up your target database

Now that you have the Local Zone enabled with a subnet, set up your target database instance in the Local Zone subnet that you just created.

You can use AWS CLI to launch it as an EC2 instance:

aws ec2 run-instances \
  --region us-east-1 \
  --subnet-id subnet-08fc749671example \
  --instance-type t3.medium \
  --image-id ami-0abcdef123example \
  --security-group-ids sg-0b0384b66dexample \
  --key-name my-key-pair

You can verify that your EC2 instance is running with the following command:

aws ec2 describe-instances --filters "Name=availability-zone,Values=us-east-1-qro-1a" --query "Reservations[].Instances[].InstanceId"

Output:

 $ ["i-0cda255374example"]

Note that not all instance types are available in Local Zones. You can verify it with the following AWS CLI command:

aws ec2 describe-instance-type-offerings --location-type "availability-zone" \
--filters Name=location,Values=us-east-1-qro-1a --region us-east-1

Once you have your instance running in the Local Zone, you can install the database engine matching your source database. Here is an example of how to install MariaDB:

  1. Updates all packages to the latest OS versionsudo yum update -y
  2. Install MySQL server on your instance, this also creates a systemd servicesudo yum install -y mariadb-server
  3. Enable the service created in previous stepsudo systemctl enable mariadb
  4. Start the MySQL server service on your Amazon Linux instancesudo systemctl start mariadb
  5. Set root user password and improve your DB securitysudo mysql_secure_installation

You can confirm successful installation with these commands:

mysql -h localhost -u root -p
SHOW DATABASES;

3. Configure databases for replication

In order for AWS DMS to replicate ongoing changes, you must use change data capture (CDC), as well as set up your source and target database accordingly before replication:

Source database:

  • Make sure that the binary logs are available to AWS DMS:

 call mysql.rds_set_configuration('binlog retention hours', 24);

  • Set the binlog_format parameter to “ROW“.
  • Set the binlog_row_image parameter to “Full“.
  • If you are using Read replica as source, then set the log_slave_updates parameter to TRUE.

For detailed information, refer to Using a MySQL-compatible database as a source for AWS DMS, or sources for your migration if your database engine is different.

Target database:

  • Create a user for AWS DMS that has read/write privileges to the MySQL-compatible database. To create the necessary privileges, run the following commands.
CREATE USER ''@'%' IDENTIFIED BY '';
GRANT ALTER, CREATE, DROP, INDEX, INSERT, UPDATE, DELETE, SELECT ON .* TO 
''@'%';
GRANT ALL PRIVILEGES ON awsdms_control.* TO ''@'%';
  • Disable foreign keys on target tables, by adding the next command in the Extra connection attributes section of the AWS DMS console for your target endpoint.

Initstmt=SET FOREIGN_KEY_CHECKS=0;

  • Set the database parameter local_infile = 1 to enable AWS DMS to load data into the target database.

4. Set up AWS DMS

Now that you have our Local Zone enabled with the target database ready and the source database configured, you can set up AWS DMS Replication instance.

Go to AWS DMS in the AWS Management Console, and under Migrate data select Replication Instances, then select the Create Replication button:

This shows the Create replication Instance, where you should fill up the parameters required:

Note that High Availability is set to Single-AZ, as this is a test workload, while Multi-AZ is recommended for Production workloads.

Refer to the AWS DMS replication instance documentation for details about how to size your replication instance.

Important note

To allow replication, make sure that you set up the replication instance in the VPC that your environment is running, and configure security groups from and to the source and target database.

Now you can create the DMS Source and Target endpoints:

5. Set up endpoints

Source endpoint:

In the AWS DMS console, select Endpoints, select the Create endpoint button, and select Source endpoint option. Then, fill the details required:

Make sure you select your RDS instance as Source by selecting the check box as show in the preceding figure. Moreover, include access to endpoint database details, such as user and password.

You can test your endpoint connectivity before creating it, as shown in the following figure:

If your test is successful, then you can select the Create endpoint button.

Target endpoint:

In the same way as the Source in the console, select Endpoints, select the Create endpoint button, and select Target endpoint option, then enter the details required, as shown in the following figure:

In the Access to endpoint database section, select Provide access information manually option, next add your Local Zone target database connection details as shown below. Notice that Server name value, should be the IP address of your target database.

Make sure you go to the bottom of the page and configure Extra connection attributes in the Endpoint settings, as described in the Configure databases for replication section of this post:

Like the source endpoint, you can test your endpoint connection before creating it.

6. Create the replication task

Once the endpoints are ready, you can create the migration task to start the replication. Under the Migrate Data section, select Database migration tasks, hit the Create task button, and configure your task:

Select Migrate existing data and replicate ongoing changes in the Migration type parameter.

Enable Task logs under Task Settings. This is recommended as it can help you with troubleshooting purposes.

In Table mappings, include the schema you want to replicate to the Local Zone database:

Once you have defined Task Configuration, Task Settings, and Table Mappings, you can proceed to create your database migration task.

This will trigger your migration task. Now wait until the migration task completes successfully.

7. Validate replicated database

After the replication job completes the Full Load, proceed to validate at your target database. Connect to your target database and run the following commands:

USE example;
SHOW TABLES;

As a result you should see the same tables as the source database.

MySQL [example]> SHOW TABLES;
+----------------------------+
| Tables_in_example          |
+----------------------------+
| actor                      |
| address                    |
| category                   |
| city                       |
| country                    |
| customer                   |
| customer_list              |
| film                       |
| film_actor                 |
| film_category              |
| film_list                  |
| film_text                  |
| inventory                  |
| language                   |
| nicer_but_slower_film_list |
| payment                    |
| rental                     |
| sales_by_film_category     |
| sales_by_store             |
| staff                      |
| staff_list                 |
| store                      |
+----------------------------+
22 rows in set (0.06 sec)

If you get the same tables from your source database, then congratulations, you’re set! Now you can maintain and navigate a live copy of database in the Local Zone for data residency purposes.

Clean up

When you have finished this tutorial, you can delete all the resources that have been deployed. You can do this in the Console or by running the following commands in the AWS CLI:

  1. Delete target DB:
    aws ec2 terminate-instances --instance-ids i-abcd1234
  2. Decommision AWS DMS
    • Replication Task:
      aws dms delete-replication-task --replication-task-arn arn:aws:dms:us-east-1:111111111111:task:K55IUCGBASJS5VHZJIIEXAMPLE
    • Endpoints:
      aws dms delete-endpoint --endpoint-arn arn:aws:dms:us-east-1:111111111111:endpoint:OUJJVXO4XZ4CYTSEG5XEXAMPLE
    • Replication instance:
      aws dms delete-replication-instance --replication-instance-arn us-east-1:111111111111:rep:T3OM7OUB5NM2LCVZF7JEXAMPLE
  3. Delete Local Zone subnet
    aws ec2 delete-subnet --subnet-id subnet-9example

Conclusion

Local Zones is a useful tool for running applications with low latency requirements or data residency regulations. In this post, you have learned how to use AWS DMS to seamlessly replicate your data to Local Zones. With this architecture you can efficiently maintain a local copy of your data in Local Zones and access it securly.

If you are interested on how to automate your workloads deployments in Local Zones, make sure you check this workshop.

Securing generative AI: An introduction to the Generative AI Security Scoping Matrix

Post Syndicated from Matt Saner original https://aws.amazon.com/blogs/security/securing-generative-ai-an-introduction-to-the-generative-ai-security-scoping-matrix/

Generative artificial intelligence (generative AI) has captured the imagination of organizations and is transforming the customer experience in industries of every size across the globe. This leap in AI capability, fueled by multi-billion-parameter large language models (LLMs) and transformer neural networks, has opened the door to new productivity improvements, creative capabilities, and more.

As organizations evaluate and adopt generative AI for their employees and customers, cybersecurity practitioners must assess the risks, governance, and controls for this evolving technology at a rapid pace. As security leaders working with the largest, most complex customers at Amazon Web Services (AWS), we’re regularly consulted on trends, best practices, and the rapidly evolving landscape of generative AI and the associated security and privacy implications. In that spirit, we’d like to share key strategies that you can use to accelerate your own generative AI security journey.

This post, the first in a series on securing generative AI, establishes a mental model that will help you approach the risk and security implications based on the type of generative AI workload you are deploying. We then highlight key considerations for security leaders and practitioners to prioritize when securing generative AI workloads. Follow-on posts will dive deep into developing generative AI solutions that meet customers’ security requirements, best practices for threat modeling generative AI applications, approaches for evaluating compliance and privacy considerations, and will explore ways to use generative AI to improve your own cybersecurity operations.

Where to start

As with any emerging technology, a strong grounding in the foundations of that technology is critical to helping you understand the associated scopes, risks, security, and compliance requirements. To learn more about the foundations of generative AI, we recommend that you start by reading more about what generative AI is, its unique terminologies and nuances, and exploring examples of how organizations are using it to innovate for their customers.

If you’re just starting to explore or adopt generative AI, you might imagine that an entirely new security discipline will be required. While there are unique security considerations, the good news is that generative AI workloads are, at their core, another data-driven computing workload, and they inherit much of the same security regimen. The fact is, if you’ve invested in cloud cybersecurity best practices over the years and embraced prescriptive advice from sources like Steve’s top 10, the Security Pillar of the Well-Architected Framework, and the Well-Architected Machine Learning Lens, you’re well on your way!

Core security disciplines, like identity and access management, data protection, privacy and compliance, application security, and threat modeling are still critically important for generative AI workloads, just as they are for any other workload. For example, if your generative AI application is accessing a database, you’ll need to know what the data classification of the database is, how to protect that data, how to monitor for threats, and how to manage access. But beyond emphasizing long-standing security practices, it’s crucial to understand the unique risks and additional security considerations that generative AI workloads bring. This post highlights several security factors, both new and familiar, for you to consider.

With that in mind, let’s discuss the first step: scoping.

Determine your scope

Your organization has made the decision to move forward with a generative AI solution; now what do you do as a security leader or practitioner? As with any security effort, you must understand the scope of what you’re tasked with securing. Depending on your use case, you might choose a managed service where the service provider takes more responsibility for the management of the service and model, or you might choose to build your own service and model.

Let’s look at how you might use various generative AI solutions in the AWS Cloud. At AWS, security is a top priority, and we believe providing customers with the right tool for the job is critical. For example, you can use the serverless, API-driven Amazon Bedrock with simple-to-consume, pre-trained foundation models (FMs) provided by AI21 Labs, Anthropic, Cohere, Meta, stability.ai, and Amazon Titan. Amazon SageMaker JumpStart provides you with additional flexibility while still using pre-trained FMs, helping you to accelerate your AI journey securely. You can also build and train your own models on Amazon SageMaker. Maybe you plan to use a consumer generative AI application through a web interface or API such as a chatbot or generative AI features embedded into a commercial enterprise application your organization has procured. Each of these service offerings has different infrastructure, software, access, and data models and, as such, will result in different security considerations. To establish consistency, we’ve grouped these service offerings into logical categorizations, which we’ve named scopes.

In order to help simplify your security scoping efforts, we’ve created a matrix that conveniently summarizes key security disciplines that you should consider, depending on which generative AI solution you select. We call this the Generative AI Security Scoping Matrix, shown in Figure 1.

The first step is to determine which scope your use case fits into. The scopes are numbered 1–5, representing least ownership to greatest ownership.

Buying generative AI:

  • Scope 1: Consumer app – Your business consumes a public third-party generative AI service, either at no-cost or paid. At this scope you don’t own or see the training data or the model, and you cannot modify or augment it. You invoke APIs or directly use the application according to the terms of service of the provider.
    Example: An employee interacts with a generative AI chat application to generate ideas for an upcoming marketing campaign.
  • Scope 2: Enterprise app – Your business uses a third-party enterprise application that has generative AI features embedded within, and a business relationship is established between your organization and the vendor.
    Example: You use a third-party enterprise scheduling application that has a generative AI capability embedded within to help draft meeting agendas.

Building generative AI:

  • Scope 3: Pre-trained models – Your business builds its own application using an existing third-party generative AI foundation model. You directly integrate it with your workload through an application programming interface (API).
    Example: You build an application to create a customer support chatbot that uses the Anthropic Claude foundation model through Amazon Bedrock APIs.
  • Scope 4: Fine-tuned models – Your business refines an existing third-party generative AI foundation model by fine-tuning it with data specific to your business, generating a new, enhanced model that’s specialized to your workload.
    Example: Using an API to access a foundation model, you build an application for your marketing teams that enables them to build marketing materials that are specific to your products and services.
  • Scope 5: Self-trained models – Your business builds and trains a generative AI model from scratch using data that you own or acquire. You own every aspect of the model.
    Example: Your business wants to create a model trained exclusively on deep, industry-specific data to license to companies in that industry, creating a completely novel LLM.

In the Generative AI Security Scoping Matrix, we identify five security disciplines that span the different types of generative AI solutions. The unique requirements of each security discipline can vary depending on the scope of the generative AI application. By determining which generative AI scope is being deployed, security teams can quickly prioritize focus and assess the scope of each security discipline.

Let’s explore each security discipline and consider how scoping affects security requirements.

  • Governance and compliance – The policies, procedures, and reporting needed to empower the business while minimizing risk.
  • Legal and privacy – The specific regulatory, legal, and privacy requirements for using or creating generative AI solutions.
  • Risk management – Identification of potential threats to generative AI solutions and recommended mitigations.
  • Controls – The implementation of security controls that are used to mitigate risk.
  • Resilience – How to architect generative AI solutions to maintain availability and meet business SLAs.

Throughout our Securing Generative AI blog series, we’ll be referring to the Generative AI Security Scoping Matrix to help you understand how various security requirements and recommendations can change depending on the scope of your AI deployment. We encourage you to adopt and reference the Generative AI Security Scoping Matrix in your own internal processes, such as procurement, evaluation, and security architecture scoping.

What to prioritize

Your workload is scoped and now you need to enable your business to move forward fast, yet securely. Let’s explore a few examples of opportunities you should prioritize.

Governance and compliance plus Legal and privacy

With consumer off-the-shelf apps (Scope 1) and enterprise off-the-shelf apps (Scope 2), you must pay special attention to the terms of service, licensing, data sovereignty, and other legal disclosures. Outline important considerations regarding your organization’s data management requirements, and if your organization has legal and procurement departments, be sure to work closely with them. Assess how these requirements apply to a Scope 1 or 2 application. Data governance is critical, and an existing strong data governance strategy can be leveraged and extended to generative AI workloads. Outline your organization’s risk appetite and the security posture you want to achieve for Scope 1 and 2 applications and implement policies that specify that only appropriate data types and data classifications should be used. For example, you might choose to create a policy that prohibits the use of personal identifiable information (PII), confidential, or proprietary data when using Scope 1 applications.

If a third-party model has all the data and functionality that you need, Scope 1 and Scope 2 applications might fit your requirements. However, if it’s important to summarize, correlate, and parse through your own business data, generate new insights, or automate repetitive tasks, you’ll need to deploy an application from Scope 3, 4, or 5. For example, your organization might choose to use a pre-trained model (Scope 3). Maybe you want to take it a step further and create a version of a third-party model such as Amazon Titan with your organization’s data included, known as fine-tuning (Scope 4). Or you might create an entirely new first-party model from scratch, trained with data you supply (Scope 5).

In Scopes 3, 4, and 5, your data can be used in the training or fine-tuning of the model, or as part of the output. You must understand the data classification and data type of the assets the solution will have access to. Scope 3 solutions might use a filtering mechanism on data provided through Retrieval Augmented Generation (RAG) with the help from Agents for Amazon Bedrock, for example, as an input to a prompt. RAG offers you an alternative to training or fine-tuning by querying your data as part of the prompt. This then augments the context for the LLM to provide a completion and response that can use your business data as part of the response, rather than directly embedding your data in the model itself through fine-tuning or training. See Figure 3 for an example data flow diagram demonstrating how customer data could be used in a generative AI prompt and response through RAG.

In scopes 4 and 5, on the other hand, you must classify the modified model for the most sensitive level of data classification used to fine-tune or train the model. Your model would then mirror the data classification on the data it was trained against. For example, if you supply PII in the fine-tuning or training of a model, then the new model will contain PII. Currently, there are no mechanisms for easily filtering the model’s output based on authorization, and a user could potentially retrieve data they wouldn’t otherwise be authorized to see. Consider this a key takeaway; your application can be built around your model to implement filtering controls on your business data as part of a RAG data flow, which can provide additional data security granularity without placing your sensitive data directly within the model.

From a legal perspective, it’s important to understand both the service provider’s end-user license agreement (EULA), terms of services (TOS), and any other contractual agreements necessary to use their service across Scopes 1 through 4. For Scope 5, your legal teams should provide their own contractual terms of service for any external use of your models. Also, for Scope 3 and Scope 4, be sure to validate both the service provider’s legal terms for the use of their service, as well as the model provider’s legal terms for the use of their model within that service.

Additionally, consider the privacy concerns if the European Union’s General Data Protection Regulation (GDPR) “right to erasure” or “right to be forgotten” requirements are applicable to your business. Carefully consider the impact of training or fine-tuning your models with data that you might need to delete upon request. The only fully effective way to remove data from a model is to delete the data from the training set and train a new version of the model. This isn’t practical when the data deletion is a fraction of the total training data and can be very costly depending on the size of your model.

Risk management

While AI-enabled applications can act, look, and feel like non-AI-enabled applications, the free-form nature of interacting with an LLM mandates additional scrutiny and guardrails. It is important to identify what risks apply to your generative AI workloads, and how to begin to mitigate them.

There are many ways to identify risks, but two common mechanisms are risk assessments and threat modeling. For Scopes 1 and 2, you’re assessing the risk of the third-party providers to understand the risks that might originate in their service, and how they mitigate or manage the risks they’re responsible for. Likewise, you must understand what your risk management responsibilities are as a consumer of that service.

For Scopes 3, 4, and 5—implement threat modeling—while we will dive deep into specific threats and how to threat-model generative AI applications in a future blog post, let’s give an example of a threat unique to LLMs. Threat actors might use a technique such as prompt injection: a carefully crafted input that causes an LLM to respond in unexpected or undesired ways. This threat can be used to extract features (features are characteristics or properties of data used to train a machine learning (ML) model), defame, gain access to internal systems, and more. In recent months, NIST, MITRE, and OWASP have published guidance for securing AI and LLM solutions. In both the MITRE and OWASP published approaches, prompt injection (model evasion) is the first threat listed. Prompt injection threats might sound new, but will be familiar to many cybersecurity professionals. It’s essentially an evolution of injection attacks, such as SQL injection, JSON or XML injection, or command-line injection, that many practitioners are accustomed to addressing.

Emerging threat vectors for generative AI workloads create a new frontier for threat modeling and overall risk management practices. As mentioned, your existing cybersecurity practices will apply here as well, but you must adapt to account for unique threats in this space. Partnering deeply with development teams and other key stakeholders who are creating generative AI applications within your organization will be required to understand the nuances, adequately model the threats, and define best practices.

Controls

Controls help us enforce compliance, policy, and security requirements in order to mitigate risk. Let’s dive into an example of a prioritized security control: identity and access management. To set some context, during inference (the process of a model generating an output, based on an input) first- or third-party foundation models (Scopes 3–5) are immutable. The API to a model accepts an input and returns an output. Models are versioned and, after release, are static. On its own, the model itself is incapable of storing new data, adjusting results over time, or incorporating external data sources directly. Without the intervention of data processing capabilities that reside outside of the model, the model will not store new data or mutate.

Both modern databases and foundation models have a notion of using the identity of the entity making a query. Traditional databases can have table-level, row-level, column-level, or even element-level security controls. Foundation models, on the other hand, don’t currently allow for fine-grained access to specific embeddings they might contain. In LLMs, embeddings are the mathematical representations created by the model during training to represent each object—such as words, sounds, and graphics—and help describe an object’s context and relationship to other objects. An entity is either permitted to access the full model and the inference it produces or nothing at all. It cannot restrict access at the level of specific embeddings in a vector database. In other words, with today’s technology, when you grant an entity access directly to a model, you are granting it permission to all the data that model was trained on. When accessed, information flows in two directions: prompts and contexts flow from the user through the application to the model, and a completion returns from the model back through the application providing an inference response to the user. When you authorize access to a model, you’re implicitly authorizing both of these data flows to occur, and either or both of these data flows might contain confidential data.

For example, imagine your business has built an application on top of Amazon Bedrock at Scope 4, where you’ve fine-tuned a foundation model, or Scope 5 where you’ve trained a model on your own business data. An AWS Identity and Access Management (IAM) policy grants your application permissions to invoke a specific model. The policy cannot limit access to subsets of data within the model. For IAM, when interacting with a model directly, you’re limited to model access.

{
	"Version": "2012-10-17",
	"Statement": {
		"Sid": "AllowInference",
		"Effect": "Allow",
		"Action": [
			"bedrock:InvokeModel"
		],
		"Resource": "arn:aws:bedrock:*::<foundation-model>/<model-id-of-model-to-allow>
	}
}

What could you do to implement least privilege in this case? In most scenarios, an application layer will invoke the Amazon Bedrock endpoint to interact with a model. This front-end application can use an identity solution, such as Amazon Cognito or AWS IAM Identity Center, to authenticate and authorize users, and limit specific actions and access to certain data accordingly based on roles, attributes, and user communities. For example, the application could select a model based on the authorization of the user. Or perhaps your application uses RAG by querying external data sources to provide just-in-time data for generative AI responses, using services such as Amazon Kendra or Amazon OpenSearch Serverless. In that case, you would use an authorization layer to filter access to specific content based on the role and entitlements of the user. As you can see, identity and access management principles are the same as any other application your organization develops, but you must account for the unique capabilities and architectural considerations of your generative AI workloads.

Resilience

Finally, availability is a key component of security as called out in the C.I.A. triad. Building resilient applications is critical to meeting your organization’s availability and business continuity requirements. For Scope 1 and 2, you should understand how the provider’s availability aligns to your organization’s needs and expectations. Carefully consider how disruptions might impact your business should the underlying model, API, or presentation layer become unavailable. Additionally, consider how complex prompts and completions might impact usage quotas, or what billing impacts the application might have.

For Scopes 3, 4, and 5, make sure that you set appropriate timeouts to account for complex prompts and completions. You might also want to look at prompt input size for allocated character limits defined by your model. Also consider existing best practices for resilient designs such as backoff and retries and circuit breaker patterns to achieve the desired user experience. When using vector databases, having a high availability configuration and disaster recovery plan is recommended to be resilient against different failure modes.

Instance flexibility for both inference and training model pipelines are important architectural considerations in addition to potentially reserving or pre-provisioning compute for highly critical workloads. When using managed services like Amazon Bedrock or SageMaker, you must validate AWS Region availability and feature parity when implementing a multi-Region deployment strategy. Similarly, for multi-Region support of Scope 4 and 5 workloads, you must account for the availability of your fine-tuning or training data across Regions. If you use SageMaker to train a model in Scope 5, use checkpoints to save progress as you train your model. This will allow you to resume training from the last saved checkpoint if necessary.

Be sure to review and implement existing application resilience best practices established in the AWS Resilience Hub and within the Reliability Pillar and Operational Excellence Pillar of the Well Architected Framework.

Conclusion

In this post, we outlined how well-established cloud security principles provide a solid foundation for securing generative AI solutions. While you will use many existing security practices and patterns, you must also learn the fundamentals of generative AI and the unique threats and security considerations that must be addressed. Use the Generative AI Security Scoping Matrix to help determine the scope of your generative AI workloads and the associated security dimensions that apply. With your scope determined, you can then prioritize solving for your critical security requirements to enable the secure use of generative AI workloads by your business.

Please join us as we continue to explore these and additional security topics in our upcoming posts in the Securing Generative AI series.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Matt Saner

Matt Saner

Matt is a Senior Manager leading security specialists at AWS. He and his team help the world’s largest and most complex organizations solve critical security challenges, and help security teams become enablers for their business. Before joining AWS, Matt spent nearly two decades working in the financial services industry, solving various technology, security, risk, and compliance challenges. He highly values life-long learning (security is never static) and holds a Masters in Cybersecurity from NYU. For fun, he’s a pilot who enjoys flying general aviation airplanes.

Mike Lapidakis

Mike Lapidakis

Mike leads the AWS Industries Specialist SA team, comprised of the Security and Compliance, Migration and Modernization, Networking, and Resilience domains. The team helps the largest customers on earth establish a strong foundation to transform their businesses through technical enablement, education, customer advocacy, and executive alignment. Mike has helped organizations modernize on the cloud for over a decade in various architecture and consulting roles.