Tag Archives: Best practices

Looking beyond code coverage with Amazon CodeWhisperer

Post Syndicated from Saurabh Kumar original https://aws.amazon.com/blogs/devops/looking-beyond-code-coverage-with-amazon-codewhisperer/

Code coverage is a code quality metric leveraging unit tests. Coming up with test cases with every combination of parameters requires developer’s time, which is already scarce. Developers’ focus is (mis)directed at just meeting the coverage threshold. In doing so, quality of code may be compromised and resulting code may still result in unexpected outcomes.

In this blog, we will walk you through a Java application and demonstrate how to look beyond code coverage by leveraging Amazon CodeWhisperer, an AI coding companion, for generating a combination of test cases, including boundary conditions which are often overlooked due to time and resource constraints. Taking this approach, you can improve code quality as well as improve your productivity.

Prerequisites

  1. Create an AWS Account. If you don’t already have an AWS account, you’ll need to create one in order to follow the steps outlined to AWS Management Console. For this, it is recommended to create a new user.
  2. To set up CodeWhisperer for your development environment, follow the setup instructions AWS Toolkit.
  3. Download and set up Java: Install the Java SE Development Kit.
  4. Install Maven.
  5. You can use any IDE of your choice such as Eclipse, Spring Tools, VS Code or IntelliJ. For this blog, we have used IntelliJ community edition which you can download from here. You can use IntelliJ Ultimate if you have a license for it.
  6. Clone repo: Looking beyond code coverage with CodeWhisperer.
  7. Import cloned project in IntelliJ following importing-a-project guide.

Following the above steps, you would have setup the project locally. Figure1 below shows how the initial project should look after you have imported it as maven project in your IDE:

Figure1. initial Java project

Figure1. initial Java project

The following screen recording shows how you can use CodeWhisperer to generate code for ‘add’ method using the comment “//method for adding two numbers”.

ScreenRecording 1. Initial application code generation

ScreenRecording 1. Initial application code generation

Now let’s generate one simple test case using CodeWhisperer as shown in the ScreenRecording 2. First test case generation:

ScreenRecording 2. First test case generation

ScreenRecording 2. First test case generation

Let’s run the test case with code coverage. In figure2. “First test with code coverage”, you can see that we have achieved 100% coverage on the Calculator class. If we just go by the coverage, we can conclude that the code is ready.

Figure2. First test with code coverage

Figure2. First test with code coverage

Just one unit test is not sufficient to ensure quality and side-effect-free code. Next, you will see how CodeWhisperer can assist in generating additional test cases. As soon as you begin typing a comment like, “// Test,” it provides suggestions for new test cases, such as “// test with one negative number,” “// test with two negative numbers,” “Test with one zero number,” etc. This feature, as shown in the ScreenRecording 3 titled ‘Generating additional test cases’ below, makes the task of generating a variety of test cases easier and enables developers to create more tests in a shorter amount of time.

ScreenRecording 3. Generating additional test cases

ScreenRecording 3. Generating additional test cases

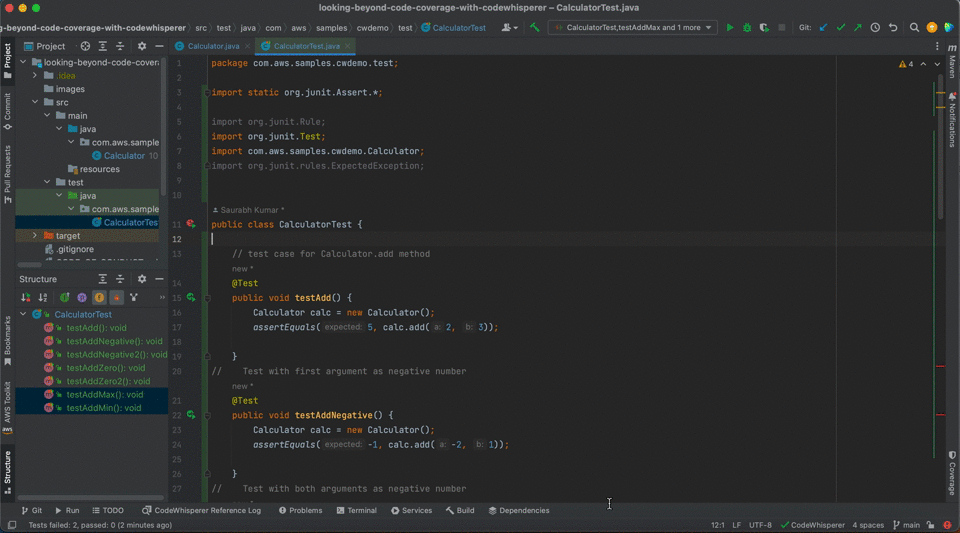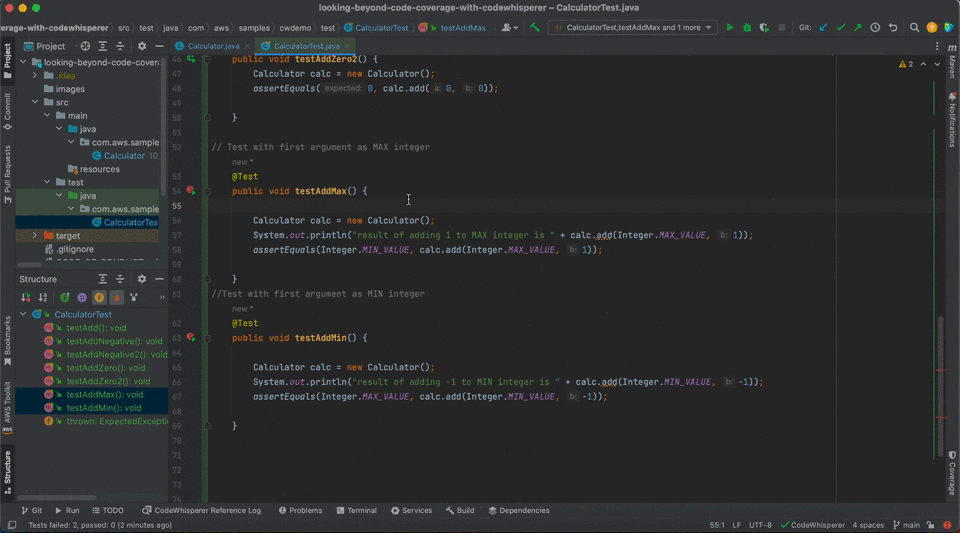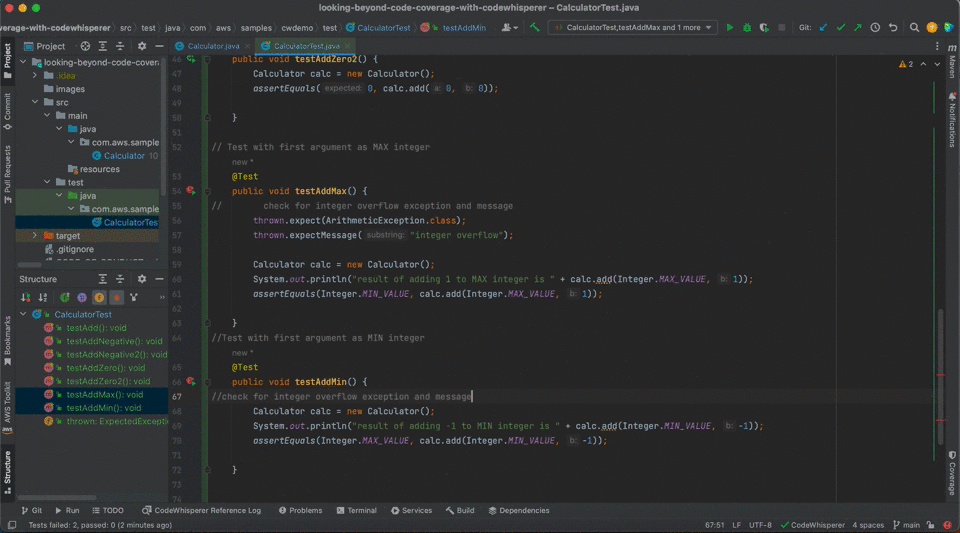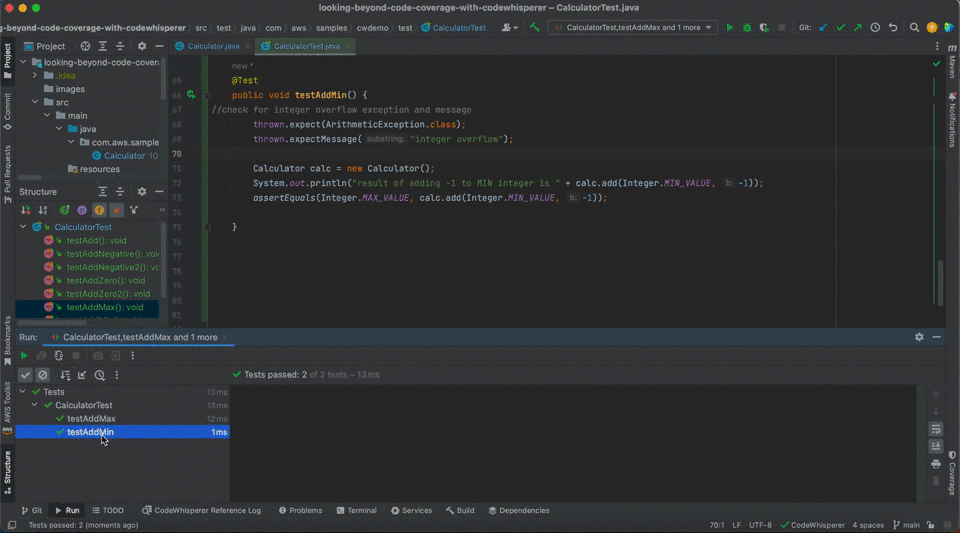
So far, we have generated test cases with different arguments and still have 100% code coverage. Let’s now turn our focus towards safety of the code and think about different arguments that can lead to unexpected outcomes. Each argument should fall within the range of -2,147,483,648 (the minimum value of type int) to 2,147,483,647 (the maximum value of type int). Let’s use CodeWhisperer to generate additional test cases to challenge code safety as shown in the screen recording below:

ScreenRecording 4. Generating test for boundary conditions

ScreenRecording 4. Generating test for boundary conditions

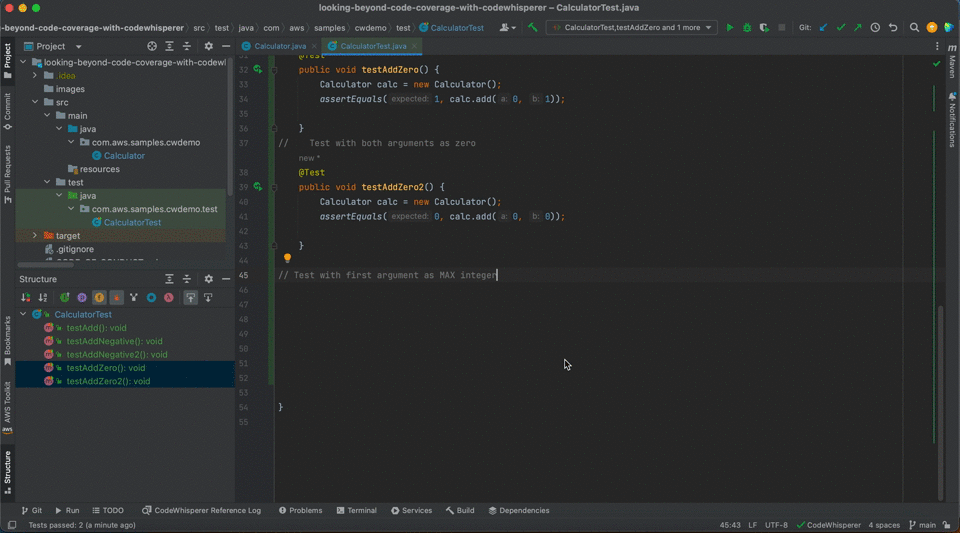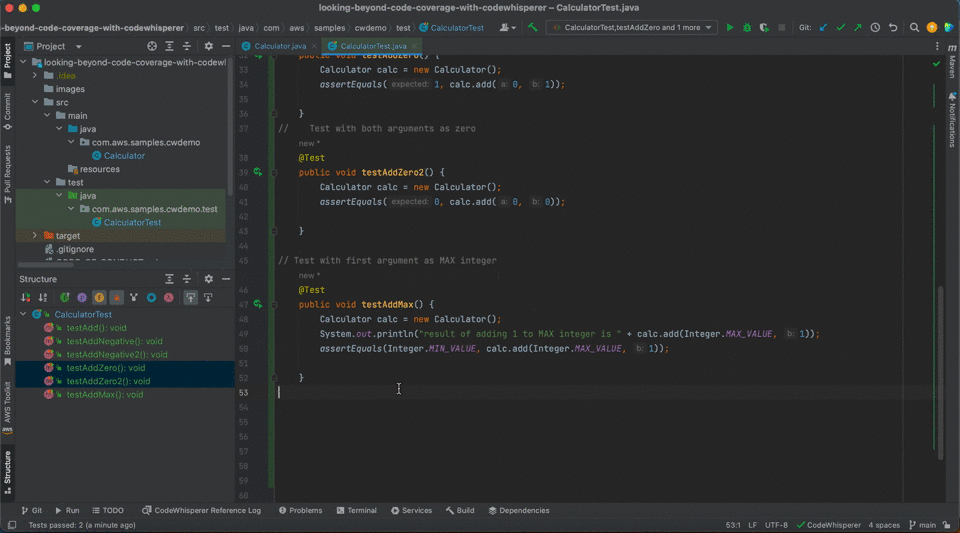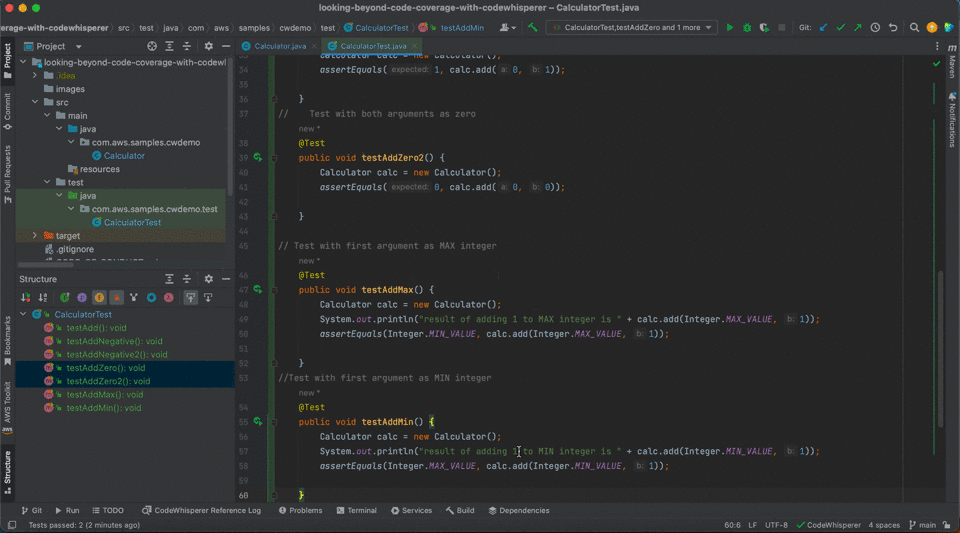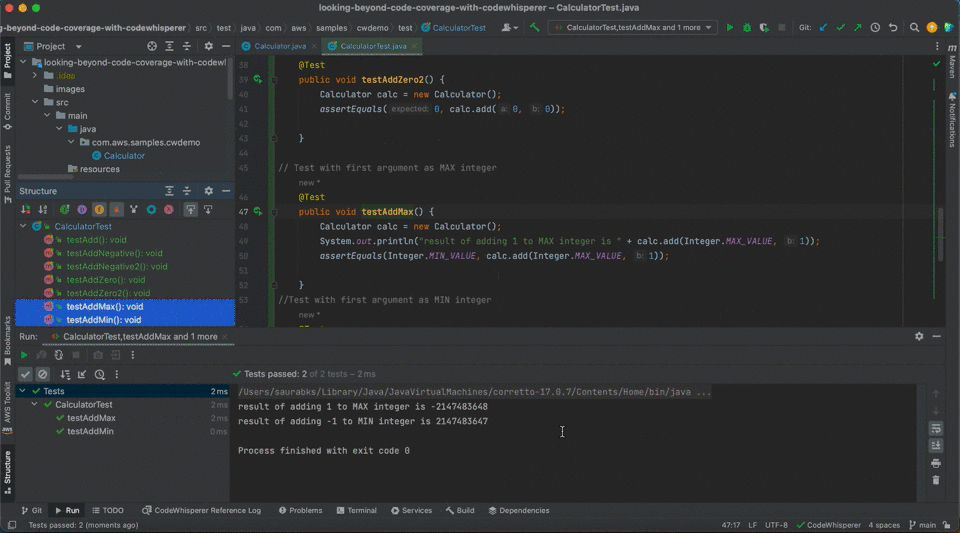
Here, CodeWhisperer first generated a test case which adds 1 to maximum value of integer. We have also added a statement to print the result to console so that we can see the actual value ‘add’ method returns when this use case is executed. Point to note here: the generated test case is expecting the output to be the MINIMUM value of type int. Upon execution, the test case prints something unexpected. Because of the way signed integer operations work, adding 1 to max int results in the min value.

Let’s consider this in more practical terms. Imagine using the ‘add’ method in a banking system, where every time a customer deposits money into their bank account, you add up the recent deposit to calculate the final amount in their account. Now, imagine a customer’s reaction when they find their balance to be negative after depositing $2.14 billion, and they now owe huge overdraft charges.

This example demonstrates that even code with 100% coverage has unexpected side effects. The focus should be identifying combinations of parameters which can potentially produce unexpected outcomes so that code can be corrected before it manifests this behavior in production.

Now, let’s use CodeWhisperer to generate another test case that could create an unexpected result: “add -1 to the minimum value of ‘int’”. Again, adding -1 to the minimum int value results in the MAXIMUM value. Using the same example as above, a customer would be more than happy to notice that they still have money in their bank account, even after withdrawing $2.14 billion.

Again, the point is that developers should focus on ensuring that the code doesn’t have unwanted, unexpected consequences, rather than chasing a coverage target.

Now that we have seen that the add methods runs into integer overflow in certain conditions, let’s improve the code using CodeWhisperer using comment “check a and b for integer overflow”:

ScreenRecording 5. Code improvement- overflow check

ScreenRecording 5. Code improvement- overflow check

After adding the safety checks, the test cases are not resulting in unexpected outcomes and resulting in ArithmaticException as shown in the above screen recording. However, the test cases are failing, and failing test cases can interrupt the CI/CD pipeline. So, let’s refactor these test cases to expect this runtime exception and pass the test case as shown in the screen recording below.

ScreenRecording 6. Test case improvement- overflow checks

ScreenRecording 6. Test case improvement- overflow checks

Having rerun the test cases with coverage, you can see that the test cases are not only passing, but also have 100% code coverage.

For this blog, the majority of the code and its corresponding test cases are generated by CodeWhisperer, an AI coding companion. This tool enables us to enhance code by easily exploring libraries. In our example, this led us to the ‘Math.addExact’ method, which provides checks for boundary conditions relevant to our task. Let’s refactor the code to utilize this method, as shown below in Figure 3 final code.

Figure 3. Final code

Figure 3. Final code

If we rerun the test suite with coverage, we find that all the test cases are passing and coverage is also maintained at 100%.

Figure 4. Final tests with coverage

Figure 4. Final tests with coverage

Conclusion:

Through this blog post, we have demonstrated that high code coverage alone does not guarantee high quality code. Tools like Amazon CodeWhisperer can boost developer productivity by generating code and as well as corresponding test suite, including boundary conditions. This frees up developers to concentrate on business logic and to learn new frameworks and libraries, thereby resulting in overall improvement in quality and safety of code.

While our example focused on Java, this concept applies to other programming languages as well. Checkout the complete list of programming languages and IDEs supported by CodeWhisperer in the FAQs.

Try out CodeWhisperer Individual Tier for free to see how it can help you write high-quality code more efficiently using CodeWhisperer getting started guides.

Happy coding!

      
Saurabh Kumar's picture

Saurabh Kumar

Saurabh Kumar is a Solutions Architect at AWS based out of Raleigh, NC. He is passionate about helping customers solve their business challenges and technical problems from migration to modernization and optimization. Outside of work, he likes gardening and spending time with his family.

Bineesh Ravindran's picture

Bineesh Ravindran

Bineesh is Solutions Architect at Amazon Webservices (AWS) who is passionate about technology and love to help customers solve problems. Bineesh has over 20 years of experience in designing and implementing enterprise applications. He works with AWS partners and customers to provide them with architectural guidance for building scalable architecture and execute strategies to drive adoption of AWS services. When he’s not working, he enjoys biking, aqua scaping and playing badminton.

Optimizing video encoding with FFmpeg using NVIDIA GPU-based Amazon EC2 instances

Post Syndicated from Macey Neff original https://aws.amazon.com/blogs/compute/optimizing-video-encoding-with-ffmpeg-using-nvidia-gpu-based-amazon-ec2-instances/

This post is written by Alejandro Gil, Solutions Architect and Joseba Echevarría, Solutions Architect. 

Introduction

The purpose of this blog post is to compare video encoding performance between CPUs and Nvidia GPUs to determine the price/performance ratio in different scenarios while highlighting where it would be best to use a GPU.

Video encoding plays a critical role in modern media delivery, enabling efficient storage, delivery, and playback of high-quality video content across a wide range of devices and platforms.

Video encoding is frequently performed solely by the CPU because of its widespread availability and flexibility. Still, modern hardware includes specialized components designed specifically to obtain very high performance video encoding and decoding.

Nvidia GPUs, such as those found in the P and G Amazon EC2 instances, include this kind of built-in hardware in their NVENC (encoding) and NVDEC (decoding) accelerator engines, which can be used for real-time video encoding/decoding with minimal impact on the performance of the CPU or GPU.

NVIDIA NVDEC/NVENC architecture. Source https://developer.nvidia.com/video-codec-sdk

Figure 1: NVIDIA NVDEC/NVENC architecture. Source https://developer.nvidia.com/video-codec-sdk

Scenario

Two main transcoding job types should be considered depending on the video delivery use case, 1) batch jobs for on demand video files and 2) streaming jobs for real-time, low latency use cases. In order to achieve optimal throughput and cost efficiency, it is a best practice to encode the videos in parallel using the same instance.

The utilized instance types in this benchmark can be found in figure 2 table (i.e g4dn and p3). For hardware comparison purposes, the p4d instance has been included in the table, showing the GPU specs and total number of NVDEC & NVENC cores in these EC2 instances. Based on the requirements, multiple GPU instances types are available in EC2.

Instance size GPUs GPU model NVDEC generation NVENC generation NVDEC cores/GPU NVENC cores/GPU
g4dn.xlarge 1 T4 4th 7th 2 1
p3.2xlarge 1 V100 3rd 6th 1 3
p4d.24xlarge 8 A100 4th N/A 5 0

Figure 2: GPU instances specifications

Benchmark

In order to determine which encoding strategy is the most convenient for each scenario, a benchmark will be conducted comparing CPU and GPU instances across different video settings. The results will be further presented using graphical representations of the performance indicators obtained.

The benchmark uses 3 input videos with different motion and detail levels (still, medium motion and high dynamic scene) in 4k resolution at 60 frames per second. The tests will show the average performance for encoding with FFmpeg 6.0 in batch (using Constant Rate Factor (CRF) mode) and streaming (using Constant Bit Rate (CBR)) with x264 and x265 codecs to five output resolutions (1080p, 720p, 480p, 360p and 160p).

The benchmark tests encoding the target videos into H.264 and H.265 using the x264 and x265 open-source libraries in FFmpeg 6.0 on the CPU and the NVENC accelerator when using the Nvidia GPU. The H.264 standard enjoys broad compatibility, with most consumer devices supporting accelerated decoding. The H.265 standard offers superior compression at a given level of quality than H.264 but hardware accelerated decoding is not as widely deployed. As a result, for most media delivery scenarios having more than one video format will be required in order to provide the best possible user experience.

Offline (batch) encoding

This test consists of a batch encoding with two different standard presets (ultrafast and medium for CPU-based encoding and p1 and medium presets for GPU-accelerated encoding) defined in the FFmpeg guide.

The following chart shows the relative cost of transcoding 1 million frames to the 5 different output resolutions in parallel for CPU-encoding EC2 instance (c6i.4xlarge) and two types of GPU-powered instances (g4dn.xlarge and p3.2xlarge). The results are normalized so that the cost of x264 ultrafast preset on c6i.4xlarge is equal to one.

Batch encoding performance for CPU and GPU instances.

Figure 3: Batch encoding performance for CPU and GPU instances.

The performance of batch encoding in the best GPU instance (g4dn.xlarge) shows around 73% better price/performance in x264 compared to the c6i.4xlarge and around 82% improvement in x265.

A relevent aspect to have in consideration is that the presets used are not exactly equivalent for each hardware because FFmpeg uses different operators depending on where the process runs (i.e CPU or GPU). As a consequence, the video outputs in each case have a noticeable difference between them. Generally, NVENC-based encoded videos (GPU) tend to have a higher quality in H.264, whereas CPU outputs present more encoding artifacts. The difference is more noticeable for lower quality cases (ultrafast/p1 presets or streaming use cases).

The following images compare the output quality for the medium motion video in the ultrafast/p1 and medium presets.

It is clearly seen in the following example, that the h264_nevenc (GPU) codec outperforms the libx264 codec (CPU) in terms of quality, showing less pixelation, especially in the ultrafast preset. For the medium preset, although the quality difference is less pronounced, the GPU output file is noticeably larger (refer to Figure 6 table).

Result comparison between GPU and CPU for h264, ultrafast

Figure 4: Result comparison between GPU and CPU for h264, ultrafast

Result comparison between GPU and CPU for h264, medium

Figure 5: Result comparison between GPU and CPU for h264, medium

The output file sizes mainly depend on the preset, codec and input video. The different configurations can be found in the following table.

Sizes for output batch encoded videos. Streaming not represented because the size is the same (fixed bitrate)

Figure 6: Sizes for output batch encoded videos. Streaming not represented because the size is the same (fixed bitrate)

Live stream encoding

For live streaming use cases, it is useful to measure how many streams a single instance can maintain transcoding to five output resolutions (1080p, 720p, 480p, 360p and 160p). The following results are the relative cost of each instance, which is the ratio of number of streams the instance was able to sustain divided by the cost per hour.

Streaming encoding performance for CPU and GPU instances.

Figure 6: Streaming encoding performance for CPU and GPU instances.

The previous results show that a GPU-based instance family like g4dn is ideal for streaming use cases, where they can sustain up to 4 parallel encodings from 4K to 1080p, 720p, 480p, 360p & 160p simultaneously. Notice that the GPU-based p5 family performance is not compensating the cost increase.

On the other hand, the CPU-based instances can sustain 1 parallel stream (at most). If you want to sustain the same number of parallel streams in Intel-based instances, you’d have to opt for a much larger instance (c6i.12xlarge can almost sustain 3 simultaneous streams, but it struggles to keep up with the more dynamic scenes when encoding with x265) with a much higher cost ($2.1888 hourly for c6i.12xlarge vs $0.587 for g4dn.xlarge).

The price/performance difference is around 68% better in GPU for x264 and 79% for x265.

Conclusion

The results show that for the tested scenarios there can be a price-performance gain when transcoding with GPU compared to CPU. Also, GPU-encoded videos tend to have an equal or higher perceived quality level to CPU-encoded counterparts and there is no significant performance penalty for encoding to the more advanced H.265 format, which can make GPU-based encoding pipelines an attractive option.

Still, CPU-encoders do a particularly good job with containing output file sizes for most of the cases we tested, producing smaller output file sizes even when the perceived quality is simmilar. This is an important aspect to have into account since it can have a big impact in cost. Depending on the amount of media files distributed and consumed by final users, the data transfer and storage cost will noticeably increase if GPUs are used. With this in mind, it is important to weight the compute costs with the data transfer and storage costs for your use case when chosing to use CPU or GPU-based video encoding.

One additional point to be considered is pipeline flexibility. Whereas the GPU encoding pipeline is rigid, CPU-based pipelines can be modified to the customer’s needs, including  additional FFmpeg filters to accommodate future needs as required.

The test did not include any specific quality measurements in the transcoded images, but it would be interesting to perform an analysis based on quantitative VMAF (or similar algorithm) metrics for the videos. We always recommend to make your own test to validate if the results obtained meet your requirements.

Benchmarking method

This blog post extends on the original work described in Optimized Video Encoding with FFmpeg on AWS Graviton Processors and the benchmarking process has been maintained in order to preserve consistency of the benchmark results. The original article analyzes in detail the price/performance advantages of AWS Graviton 3 compared to other processors.

Batch encoding workflow

Figure 7: Batch encoding workflow

Best Practices for Prompt Engineering with Amazon CodeWhisperer

Post Syndicated from Brendan Jenkins original https://aws.amazon.com/blogs/devops/best-practices-for-prompt-engineering-with-amazon-codewhisperer/

Generative AI coding tools are changing the way developers accomplish day-to-day development tasks. From generating functions to creating unit tests, these tools have helped customers accelerate software development. Amazon CodeWhisperer is an AI-powered productivity tools for the IDE and command line that helps improve developer productivity by providing code recommendations based on developers’ natural language comments and surrounding code. With CodeWhisperer, developers can simply write a comment that outlines a specific task in plain English, such as “create a lambda function to upload a file to S3.”

When writing these input prompts to CodeWhisperer like the natural language comments, one important concept is prompt engineering. Prompt engineering is the process of refining interactions with large language models (LLMs) in order to better refine the output of the model. In this case, we want to refine our prompts provided to CodeWhisperer to produce better code output.

In this post, we’ll explore how to take advantage of CodeWhisperer’s capabilities through effective prompt engineering in Python. A well-crafted prompt lets you tap into the tool’s full potential to boost your productivity and help generate the correct code for your use case. We’ll cover prompt engineering best practices like writing clear, specific prompts and providing helpful context and examples. We’ll also discuss how to iteratively refine prompts to produce better results.

Prompt Engineering with CodeWhisperer

We will demonstrate the following best practices when it comes to prompt engineering with CodeWhisperer.

  • Keep your prompt specific and concise
  • Additional context in prompts
  • Utilizing multiple comments
  • Context taken from comments and code
  • Generating unit tests with cross file context
  • Prompts with cross file context

Prerequisites

The following prerequisites are required to experiment locally:

CodeWhisperer User Actions

Reference the following user actions documentation for CodeWhisperer user actions according to your IDE. In this documentation, you will see how to accept a recommendation, cycle through recommendation options, reject a recommendation, and manually trigger CodeWhisperer.

Keep prompts specific & concise

In this section, we will cover keeping your prompt specific and concise. When crafting prompts for CodeWhisperer, conciseness while maintaining objectives in your prompt is important.  Overly complex prompts lead to poor results. A good prompt contains just enough information to convey the request clearly and concisely. For example, if you prompt CodeWhisperer “create a function that eliminates duplicates lines in a text file”. This is an example of a specific and concise prompt. On the other hand, a prompt such as “create a function to look for lines of code that are seen multiple times throughout the file and delete them” may be unclear and overly wordy. In summary, focused, straightforward prompts helps CodeWhisperer understand exactly what you want and provide better outputs.

In this example, we would like to write a function in Python that will open a CSV file and store the contents into a dictionary. We will use the following simple and concise prompt that will guide CodeWhisperer to generate recommendations. Please use the left/right arrow key to cycle through the various recommendations before you hit tab to accept the recommendation.

Example 1:

Sample comment:

#load the csv file content in a dictionary

Sample solution:

#load the csv file content in a dictionary
import csv
def csv_to_dict(csv_file):
    with open(csv_file, 'r') as f:
        reader = csv.DictReader(f)
        return list(reader)

Simple and concise prompts are crucial in prompt engineering because they help CodeWhisperer understand the key information without confusion from extraneous details. Simplicity and brevity enable faster iteration and allow prompts to maximize impact within character limits.

Additional context in prompts

In this section, we will cover how additional context can aid in prompt engineering. While specific and concise prompts are crucial, some additional context can aid CodeWhisperer comprehension. Concrete examples also guide CodeWhisperer if it struggles to infer expectations from just a brief prompt.

In this example, we would like to add additional context to Example 1 where we stored the CSV file content into a dictionary. Now, we have additional requirements to store the csv file content in alphabetical order and return the list keys from the dictionary. Take a look at the sample prompt below. Judicious context helps CodeWhisperer to produce higher-quality, tailored results.

Example 2:

Sample comment:

#load the csv file content in a dictionary in alphabetical order and return the list of keys

Sample solution:

#load the csv file content in a dictionary in alphabetical order and return the list of keys
import csv
def csv_to_dict(file_name):
    def read_csv_file(file_name):
    with open(file_name, 'r') as csv_file:
        csv_reader = csv.DictReader(csv_file)
        csv_dict = {}
        for row in csv_reader:
            csv_dict[row['name']] = row
            return csv_dict

Providing additional context through background details and examples can be beneficial when crafting prompts for CodeWhisperer, as long as the extra information adds useful clarity rather than obscuring the core request. The right balance of brevity and pointed contextual signals can help CodeWhisperer generate more tailored, high-quality results.

Utilizing multiple comments

In this section, we will cover how multiple comments can be a useful technique in prompt engineering. When used strategically, multiple comments allow prompt engineers to offer more context without sacrificing brevity or cluttering the prompt.

Say we would like to open a CSV file and return the list of lines in alphabetical order, remove duplicate lines, and insert a period at the end of each line from the CSV file. Take a look at the sample CodeWhisperer prompt below. Notice how you can break up multiple requirements into separate comments.

Example 3:

Sample comment:

#open a csv file and return a list of lines in alphabetical order
#Remove duplicate lines
#Insert a period at the end of each line

Sample solution:

#open a csv file and return a list of lines in alphabetical order
#Remove duplicate lines
#Insert a period at the end of each line
def open_csv(filename):
    with open(filename) as f:
        lines = f.readlines()
        lines = list(set(lines))
        lines = sorted(lines)
        for i in range(len(lines)):
            lines[i] = lines[i].rstrip() + '.'
    return lines

Multiple comments allow prompt engineers to add extended context and guidance for CodeWhisperer while keeping prompts succinct.

Context taken from comments and code

In this section, we will cover how CodeWhisperer’s context goes beyond just your comment and also looks at the surrounding code, including other functions, imports, and more. This broader context helps guide CodeWhisperer towards implementing the use case you intend with your comment.

We will now see how additional code in our project affects the responses. This time around, we will import the Pandas library to see how it effects our recommendation as compared to the previous section.

Example 4:

Sample Comment:

import pandas as pd
#open a csv file and return a list of lines in alphabetical order
#Insert a period at the end of each line
#Replace duplicate lines with a single line

Sample solution:

import pandas as pd
#open a csv file and return a list of lines in alphabetical order
#Insert a period at the end of each line
#Replace duplicate lines with a single line
def open_csv(filename):
    df = pd.read_csv(filename)
    df = df.sort_values(by='line')
    df = df.drop_duplicates(subset='line')
    df['line'] = df['line'] + '.'
    return df['line'].tolist()

By seeing Pandas imported, CodeWhisperer understands our intent is likely to leverage it in the solution. This allows it to provide a more relevant recommendation using Pandas functions like read_csv(), sort_values(), and drop_duplicates().

Overall, surrounding code context gives CodeWhisperer additional clues for the implementation you have in mind with your high-level instructions.

Prompts with cross file context

In the previous section, we saw how we were able to utilize the surrounding code that CodeWhisperer takes in as context to generate a function for our use case. In this section, we will use that same concept to generate unit tests for the function we’ve built utilizing CodeWhisperers cross file context capability. This section will demonstrate how we can use cross file context with our prompts for use cases like test driven development.

In this example, we will prompt CodeWhisperer to write a comment referencing the open_csv function in order to write unit tests. In this case, there will be a new python file in the project directory for unit testing. We will assume the file we have been working out of is “example4.py”, and the new file is “unittest.py”. We will incorporate the following comments in “unittest.py”.

Example 5:

Sample Comment in unittest.py:

#create unit tests for the open_csv function from example4.py file

Sample solution in unittest.py:

#create unit tests for the open_csv function from example4.py file
class TestOpenCsv(unittest.TestCase):
   def test_open_csv(self):
       self.assertEqual(open_csv('example4.csv'), ['a.', 'b.', 'c.'])
       self.assertEqual(open_csv('example4.csv'), ['a.', 'b.', 'c.', 'd.'])

Notice how CodeWhisperer is using context from one file to generate code recommendation in another file. By specifying the open_csv function within the comment of the “unittest.py”, CodeWhisperer was able to analyze the function, understand its purpose and interface, and generate a set of basic unit tests to validate it. With our prompts, we were able to utilize CodeWhisperers cross file context to help us generate unit tests.

Chain of thought prompting

Chain of thought prompting is a prompt engineering technique that allows large language models (LLMs) to have more natural, contextual outputs by linking multiple prompts together to solve a complex problem. In regard to CodeWhisperer, we can use this technique to break a very complex coding task down into smaller steps, allowing CodeWhisperer to provide more accurate suggestions to the use case.

In this example, we will examine a code snippet generated by CodeWhisperer that contains multiple comments. Our intention is to prompt the user to input a filename, ensure it’s a csv and alphanumeric, then process it with the logging.info method. We will analyze the output using both the chain of thought approach and a single comment.

Example 6:

Chain of thought prompt approach:

Comment 1 – “Take a user’s input using the input() function and store it in a variable called filename”

import logging
# Take a users input using the input() function and store it in a variable called filename
filename = input("Enter the name of the file you want to read: ")

Comment 2 – create a function that will take a filename as an input

import logging
# Take a users input using the input() function and store it in a variable called filename
filename = input("Enter the name of the file you want to read: ")

#create a function that will take a filename as an input
def open_file(filename):

Comment 3 – validate the input using the isalnum() method and ensure the file ends in .csv then process the file using logging.info()

import logging
# Take a users input using the input() function and store it in a variable called filename
filename = input("Enter the name of the file you want to read: ")

#create a function that will take a filename as an input
def open_file(filename):
    #validate the input using the isalnum() method and ensure the file ends in .csv then process the file using logging.info() 
    if filename.isalnum() and filename.endswith('.csv'):
        lines = open_csv(filename)
        logging.info(lines)
        return lines
    else:
        print('Invalid file name')
        return None

Single prompt approach:

import logging
'''
Using the input() function and store it in a variable called filename and create a function 
that will validate the input using the isalnum() method and ensure the file ends in .csv then process 
the file accordingly. 
'''
def validate_file(filename):
    if filename.isalnum() and filename.endswith('.csv'):
        return True
    else:
        return False

When analyzing these side-by-side, we see that with the chain of thought prompt approach, we used multiple comments to allow CodeWhisperer to implement all our requirements including the user input, input validation, .csv verification, and logging as we broke it down into steps for CodeWhisperer to implement. On the other hand, in the case where we had a single comment implementing multiple requirements, it didn’t take all the requirements into account for this slightly more complex problem.

In conclusion, chain of thought prompting allows large language models like CodeWhisperer to produce more accurate code pertaining to the use case by breaking down complex problems into logical steps. Guiding the model through comments and prompts helps it focus on each part of the task sequentially. This results in code that is more accurate to the desired functionality compared to a single broad prompt.

Conclusion

Effective prompt engineering is key to getting the most out of powerful AI coding assistants like Amazon CodeWhisperer. Following prompt best practices, we’ve covered like using clear language, providing context, and iteratively refining prompts can help CodeWhisperer generate high-quality code tailored to your specific needs. Analyzing all the code options CodeWhisperer provides you flexibility to select the optimal approach.

About the authors:

Brendan Jenkins

Brendan Jenkins is a Solutions Architect at Amazon Web Services (AWS) working with Enterprise AWS customers providing them with technical guidance and helping achieve their business goals. He has an area of specialization in DevOps and Machine Learning technology.

Riya Dani

Riya Dani is a Solutions Architect at Amazon Web Services (AWS), responsible for helping Enterprise customers on their journey in the cloud. She has a passion for learning and holds a Bachelor’s and Master’s degree from Virginia Tech in Computer Science with focus in Deep Learning. In her free time, she enjoys staying active and reading.

Amazon OpenSearch Serverless now supports automated time-based data deletion 

Post Syndicated from Satish Nandi original https://aws.amazon.com/blogs/big-data/amazon-opensearch-serverless-now-supports-automated-time-based-data-deletion/

We recently announced a new enhancement to OpenSearch Serverless for managing data retention of Time Series collections and Indexes. OpenSearch Serverless for Amazon OpenSearch Service makes it straightforward to run search and analytics workloads without having to think about infrastructure management. With the new automated time-based data deletion feature, you can specify how long they want to retain data and OpenSearch Serverless automatically manages the lifecycle of the data based on this configuration.

To analyze time series data such as application logs and events in OpenSearch, you must create and ingest data into indexes. Typically, these logs are generated continuously and ingested frequently, such as every few minutes, into OpenSearch. Large volumes of logs can consume a lot of the available resources such as storage in the clusters and therefore need to be managed efficiently to maximize optimum performance. You can manage the lifecycle of the indexed data by using automated tooling to create daily indexes. You can then use scripts to rotate the indexed data from the primary storage in clusters to a secondary remote storage to maintain performance and control costs, and then delete the aged data after a certain retention period.

The new automated time-based data deletion feature in OpenSearch Serverless minimizes the need to manually create and manage daily indexes or write data lifecycle scripts. You can now create a single index and OpenSearch Serverless will handle creating a timestamped collection of indexes under one logical grouping automatically. You only need to configure the desired data retention policies for your time series data collections. OpenSearch Serverless will then efficiently roll over indexes from primary storage to Amazon Simple Storage Service(Amazon S3) as they age, and automatically delete aged data per the configured retention policies, reducing the operational overhead and saving costs.

In this post we discuss the new data lifecycle polices and how to get started with these polices in OpenSearch Serverless

Solution Overview

Consider a use case where the fictitious  company Octank Broker collects logs from its web services and ingests them into OpenSearch Serverless for service availability analysis. The company is interested in tracking web access and root cause when failures are seen with error types 4xx and 5xx. Generally, the server issues are of interest within an immediate timeframe, say in a few days. After 30 days, these logs are no longer of interest.

Octank wants to retain their log data for 7 days. If the collections or indexes are configured for 7 days’ data retention, then after 7 days, OpenSearch Serverless deletes the data. The indexes are no longer available for search. Note: Document counts in search results might reflect data that is marked for deletion for a short time.

You can configure data retention by creating a data lifecycle policy. The retention time can be unlimited, or a you can provide a specific time length in Days and Hours with a minimum retention of 24 hours and a maximum of 10 years. If the retention time is unlimited, as the name suggests, no data is deleted.

To start using data lifecycle policies in OpenSearch Serverless, you can follow the steps outlined in this post.

Prerequisites

This post assumes that you have already set up an OpenSearch Serverless collection. If not, refer to Log analytics the easy way with Amazon OpenSearch Serverless for instructions.

Create a data lifecycle policy

You can create a data lifecycle policy from the AWS Management Console, the AWS Command Line Interface (AWS CLI), AWS CloudFormation, AWS Cloud Development Kit (AWS CDK), and Terraform. To create a data lifecycle policy via the console, complete the following steps:

  • On the OpenSearch Service console, choose Data lifecycle policies under Serverless in the navigation pane.
  • Choose Create data lifecycle policy.
  • For Data lifecycle policy name, enter a name (for example, web-logs-policy).
  • Choose Add under Data lifecycle.
  • Under Source Collection, choose the collection to which you want to apply the policy (for example, web-logs-collection).
  • Under Indexes, enter the index or index patterns to apply the retention duration (for example, web-logs).
  • Under Data retention, disable Unlimited (to set up the specific retention for the index pattern you defined).
  • Enter the hours or days after which you want to delete data from Amazon S3.
  • Choose Create.

The following graphic gives a quick demonstration of creating the OpenSearch Serverless Data lifecycle policies via the preceding steps.

View the data lifecycle policy

After you have created the data lifecycle policy, you can view the policy by completing the following steps:

  • On the OpenSearch Service console, choose Data lifecycle policies under Serverless in the navigation pane.
  • Select the policy you want to view (for example, web-logs-policy).
  • Choose the hyperlink under Policy name.

This page will show you the details such as the index pattern and its retention period for a specific index and collection. The following graphic gives a quick demonstration of viewing the OpenSearch Serverless data lifecycle policies via the preceding steps.

Update the data lifecycle policy

After you have created the data lifecycle policy, you can modify and update it to add more rules. For example, you can add another index pattern or add a new collection with a new index pattern to set up the retention. The following example shows the steps to add another rule in the policy for syslog index under syslogs-collection.

  • On the OpenSearch Service console, choose Data lifecycle policies under Serverless in the navigation pane.
  • Select the policy you want to edit (for example, web-logs-policy), then choose Edit.
  • Choose Add under Data lifecycle.
  • Under Source Collection, choose the collection you are going to use for setting up the data lifecycle policy (for example, syslogs-collection).
  • Under Indexes, enter index or index patterns you are going to set retention for (for example, syslogs).
  • Under Data retention, disable Unlimited (to set up specific retention for the index pattern you defined).
  • Enter the hours or days after which you want to delete data from Amazon S3.
  • Choose Save.

The following graphic gives a quick demonstration of updating existing data lifecycle policies via the preceding steps.

Delete the data lifecycle policy

Delete the existing data lifecycle policy with the following steps:

  • On the OpenSearch Service console, choose Data lifecycle policies under Serverless in the navigation pane.
  • Select the policy you want to edit (for example, web-logs-policy).
  • Choose Delete.

Data lifecycle policy rules

In a data lifecycle policy, you specify a series of rules. The data lifecycle policy lets you manage the retention period of data associated to indexes or collections that match these rules. These rules define the retention period for data in an index or group of indexes. Each rule consists of a resource type (index), a retention period, and a list of resources (indexes) that the retention period applies to.

You define the retention period with one of the following formats:

  • “MinIndexRetention”: “24h” – OpenSearch Serverless retains the index data for a specified period in hours or days. You can set this period to be from 24 hours (24h) to 3,650 days (3650d).
  • “NoMinIndexRetention”: true – OpenSearch Serverless retains the index data indefinitely.

When data lifecycle policy rules overlap, within or across policies, the rule with a more specific resource name or pattern for an index overrides a rule with a more general resource name or pattern for any indexes that are common to both rules. For example, in the following policy, two rules apply to the index index/sales/logstash. In this situation, the second rule takes precedence because index/sales/log* is the longest match to index/sales/logstash. Therefore, OpenSearch Serverless sets no retention period for the index.

Summary

Data lifecycle policies provide a consistent and straightforward way to manage indexes in OpenSearch Serverless. With data lifecycle policies, you can automate data management and avoid human errors. Deleting non-relevant data without manual intervention reduces your operational load, saves storage costs, and helps keep the system performant for search.


About the authors

Prashant Agrawal is a Senior Search Specialist Solutions Architect with Amazon OpenSearch Service. He works closely with customers to help them migrate their workloads to the cloud and helps existing customers fine-tune their clusters to achieve better performance and save on cost. Before joining AWS, he helped various customers use OpenSearch and Elasticsearch for their search and log analytics use cases. When not working, you can find him traveling and exploring new places. In short, he likes doing Eat → Travel → Repeat.

Satish Nandi is a Senior Product Manager with Amazon OpenSearch Service. He is focused on OpenSearch Serverless and has years of experience in networking, security and ML/AI. He holds a Bachelor degree in Computer Science and an MBA in Entrepreneurship. In his free time, he likes to fly airplanes, hang gliders and ride his motorcycle.

Best practices for scaling AWS CDK adoption within your organization

Post Syndicated from David Hessler original https://aws.amazon.com/blogs/devops/best-practices-for-scaling-aws-cdk-adoption-within-your-organization/

Enterprises are constantly seeking ways to accelerate their journey to the cloud. Infrastructure as code (IaC) is crucial for automating and managing cloud resources efficiently. The AWS Cloud Development Kit (AWS CDK) lets you define your cloud infrastructure as code in your favorite programming language and deploy it using AWS CloudFormation. In this post, we will discuss strategies and best practices for accelerating CDK adoption within your organization. Our discussion begins after your organization has successfully completed a pilot. In this post, you will learn how to scale the lessons learned from the pilot project across your organization through platform engineering. You will learn how to reduce complexity through building reusable components, deploy with speed and safety via builder tooling, and accelerate project startup with an internal developer portal (IDP). We will conclude by discussing ways to participate in and benefit from the broader CDK community.

Before we dive in, let’s briefly discuss a new trend in technology: Platform Engineering. DevOps practices have helped IT organizations deliver software to customers more frequently and with higher quality. A recent evolution in DevOps is the introduction of platform engineering teams to build services, toolchains, and documentation to support workload teams. An important responsibility of the platform engineering team is governance of the software delivery process.

At Amazon, we have a long and storied history of leveraging platform engineering to accelerate deployments. This is why we are able to maintain 143 different compliance certifications and attestations while deploying 150 million times per year. Platform engineering increases productivity, reduces friction between ideas and implementation, and improves agility by accelerating the delivery of workloads via a secure, scalable, and reusable set of resources and components through self-service portals and developer tools. Platform Engineering is comprised of seven capabilities: Platform Architecture, Data Architecture, Platform Product Engineering, Data Engineering, Provisioning & Orchestration, Modern App Development and CI/CD. For more information on platform engineering visit the AWS Cloud Adoption Framework.

Establishing these capabilities takes several platform and workload teams working together. From an operating model standpoint, a workload team interacts with Platform Engineering in one of the three following ways (for more information, see Building a Cloud Operating Model):

Image describes a three different cloud operating models. The first model is a transitional model where Application Engineering and Application Operations teams both supported by Cloud Platform Engineering. The second model is strategic where Application Engineering and Cloud Platform Engineering equally own the responsibility. The third model is also strategic where Application Engineering and Cloud Platform Engineering jointly own responsibility but Application Engineering owns most of the responsibility.

Reduce Builder Complexity and Cognitive load with Reusable Components

So, how can the platform team incorporate CDK to accomplish their goals? One of the common objectives of the Platform Engineering team is to publish and curate reusable patterns called Constructs. Constructs provide a mechanism to create reusable, extensible, and common components that can be shared across multiple teams and projects.

Many customers write their own implementations for constructs to enforce security best practices such as encryption and specific AWS Identity and Access Management policies. For example, you might create a MyCompanyBucket that implements your organizations security requirements in place of the default Amazon S3 Bucket construct. This bucket configuration can be implemented and extended by multiple teams to ensure they are using components that are validated by your security and compliance teams.

For customers focused on data governance, CDK constructs can automatically add in best practices for recovery time objectives and recovery point objectives by ensuring backups and architecture meet an organization’s resilience policies. For advance customers looking to enforce data lifecycle policies, create uniform access controls, or emit required KPIs, CDK constructs can provide avenues to create safe and secure configuration by default. Applying CDK constructs to DataOps, customers can benefit from templated ETL pipelines that ensure data lineage metadata is maintained and data cleansing occurs.

Customers also build constructs for non-AWS resources. Teams can build Constructs for third-party builder tooling, observability systems, testing apparatuses and more. In this way, workload teams can codify AWS and non-AWS resources in one code base. There is a balance required when writing your own constructs between ensuring standardization and providing the freedom and flexibility of taking advantage of the growing ecosystems of CDK packages. Examples of this balance include AWS Solutions Constructs, as these are typically built upon standard constructs. Without extending standard constructs, the constructs you build will be harder for consumer to integrate with the larger CDK ecosystem since it uses standardize interfaces.

Construct Hub is a central destination for discovering and sharing cloud application design patterns and reference architectures defined for CDK, that are built and published by the AWS community. While AWS provides a public Construct Hub, enterprises can maintain their private Construct Hub inside their own AWS accounts (see construct-hub, the GitHub repository, or the CDK Workshop for more details). The primary objective in either case remains consistent: to provide shared libraries that can be readily utilized by different workload teams. This approach ensures enhanced consistency, reusability, and ultimately leads to cost reduction and faster development timelines.

One of the pitfalls customers often have with leveraging this approach is that Platform Engineering cannot keep up building reusable components to leverage the latest technology enhancements. This is where leveraging the lessons learned from a pilot really can help. A pilot team works with platform engineering to research and implement security best practices. Some customers have the platform engineering team act as approvers for new constructs in addition to authors of new constructs. In this model, a pilot team works to build construct(s) for a new technology. The platform engineers approve the new construct(s). Platform engineers ensure the pilot team meets required standards such as enforcing encryption at rest, encryption in transit, and least privilege. When approval occurs, the pilot team can publish the new construct(s) to Construct Hub. In this way, platform engineering can enable experimentation and innovation, rather than become a gatekeeper. Additionally, platform engineering teams can encourage and curate an inner-sourcing model for construct creation rather than being the sole creator of constructs.

Deploy Applications Using DevSecOps Best Practices

Application builders are most productive when their expertise is channeled towards writing code that directly addresses business challenges. While creating applications is a skill well within the grasp of many software developers, the complex task of deploying and operating these applications in line with organizational standards can be overwhelming, especially for those new to a team. This complexity often acts as a bottleneck, slowing down the experimentation process and delaying the realization of value from new application initiatives.

A solution to this challenge lies in automating the deployment pipeline and operational model. By employing thoroughly tested CDK (Cloud Development Kit) components that are shared across teams and validated through a robust CI/CD (Continuous Integration/Continuous Deployment) process, the burden on developers is significantly reduced. They no longer need to delve into the complexities of the organization’s deployment strategies, allowing them to concentrate on writing unique, innovative code. This approach not only streamlines the development process but also bridges the gap between development and operations, leading to more cohesive teams and faster, more efficient releases.

One key to high-quality software delivery is to have a proper Continuous Integration and Continuous Delivery (CI/CD) process in place. You can see CDK Pipelines: Continuous delivery for AWS CDK applications for practical examples. This high-level construct, powered by AWS CodePipeline, comes in handy when you need to go beyond test deployments with the cdk deploy command and build automated pipelines for production deployments to multiple environments in different regions and/or accounts.

Whenever you commit your AWS CDK app’s source code into AWS CodeCommit, GitHub, GitLab, BitBucket, or Amazon CodeCatalyst source repository, AWS CDK Pipelines automatically builds, tests, and deploys a new version of the application. This pipeline automatically reconfigures itself to deploy as the resources in stacks changes or the environments being deployed to change. For GitHub Actions users, see CDK Pipelines for GitHub Workflows.

A number of teams are extending these pipelines and adding their own stages to ensure deployed code meets the organization’s quality, security, risk, compliance and cloud financial management criteria. For best practices of what automation to put inside the pipeline, see the AWS Deployment Pipeline Reference Architecture. By creating fully functional pipelines, platform engineering teams can reduce the cognitive load place on development teams and increase the developer experience. This strategy has two implementations: QuickStart pipelines and golden pipelines.

In QuickStart pipelines, these pipelines are created as a construct in your Construct Hub and treated similar to the above discussion on reusable components. While these pipelines offer simplified interfaces and a reduction in cognitive load, workload teams remain in control of the pipeline and are free to modify it. As a result, quality gates such as security or compliance tooling can be disabled by workload teams and controls inside the pipeline aren’t provable. This is suboptimal for organizations looking to reduce costs of compliance and audit. As the number of versions of the construct grows, teams can have difficulty governing which versions are used to ensure teams consume.

In golden pipelines, the pipelines are created as constructs, but deployed via a centralized team. Workload teams cannot control or modify these pipelines, so quality gates such as security and compliance tooling cannot be disabled. These controls become provable to stakeholders in security, risk and compliance such as auditors. Removing permissions from workload teams comes with costs. With golden pipelines, platform engineering teams often spend a majority of their time troubleshooting workload teams’ deployments. With so much time spent on troubleshooting, teams have little time to introduce new tooling to raise the security and quality standard, improve environment setup and organizational consistency, or improve audit evidence and enforcement.

Two mechanisms can augment these strategies. Traditional change control boards (CCB) can provide provability in situations where gathering evidence and enforcement are difficult. CCBs can benefit from CDK constructs that integrate IT Service Management (ITSM) approvals and fleet management processes into the pipeline and account creation processes. Alternatively, there is an emerging story with Software Supply Chain Level Artifacts (SLSA). These artifacts can be used as digital proof. In the Kubernetes space, we see this pattern with tools like Tekton chains where attestations associated with OCI images and Kyverno is used for to enforcement the presence of attestations (see Protect the pipe! Secure CI/CD pipelines with a policy-based approach using Tekton and Kyverno for details).

Multi-account and cross-region deployment with CDK

DevOps best practices suggest multiple stages of deployment and testing before deploying to production. On top of that, AWS recommends a dedicated account for each stage to simplify resource isolation and access control. This multi-account strategy helps organizations make best use of AWS resources and provides fine-grain controls (see Recommended OUs and accounts).

Often, you will have a designated AWS account, where all CI/CD pipelines reside. A deployment is executed by these pipelines to publish to other AWS accounts, which may correspond to development, staging, or production stages. For more information about a cross-account strategy in reference to CI/CD pipelines on AWS, see Building a Secure Cross-Account Continuous Delivery Pipeline.

Automated Governance

Many enterprise customers leverage CDK to enforce security controls and policies and can prevent security issues before deployment with tooling to analyze code as part of the deployment pipeline. Using the industry standard tooling of cdk-nag, many teams check applications for best practices using a combination of available rule packs. We are also seeing enterprises build their own Aspects to enforce additional requirements such as tagging requirements to manage and organize their deployed resources.

Customers can create CDK synthesized CloudFormation and add additional checkpoints with CloudFormation Guard to verify the output using policy-as-code domain-specific language (DSL) rules. Platform Engineering teams can build the rules and workload team can consume rules and run CloudFormation Guard inside the pipeline. There is an official construct that supports makes it easy to add CloudFormation Guard checks to your application.

With AWS CDK, infrastructure is code. So, the standard tooling you already use to ensure quality and improve the builder experience should be used with CDK. If your organization has a code quality program, treat CDK applications no differently than web applications or microservices. Similarly, with Amazon CodeGuru Security and Amazon CodeWhisperer, builders can get actionable recommendations on how to improve both the security and quality on their CDK code as they would with any other type of application.

With Aspects, cdk-nag, and code quality tools, organizations can prevent security issues before they are deployed. However, it is also important to create controls that work after a deployment occurs. AWS CloudFormation Hooks allow customers to inspect resources prior to create, update, or delete CloudFormation Stacks or CDK Applications. With CloudFormation Hooks, Platform Engineering teams can provide warnings or prevent provisioning resources for non-compliant resources. These hooks can be created via CDK (see Build and Deploy CloudFormation Hooks using A CI/CD Pipeline for details).

Finally, you can deploy AWS Config’s conformance packs via CDK. These collections of rules you’re your organization insist on security standards at scale. If your organization wishes to build custom rules, teams can build reactive controls using higher level constructs for AWS Config Rules. While many of these patterns existed prior to CDK, CDK helps accelerate building and deploying cloud applications and controls by leveraging reusable components that are shared within the enterprise or by the community at large.

Operate the Application using Observability

The open-source community provides high-level construct libraries that expand basic monitoring capabilities for CDK applications. The cdk-monitoring-constructs project makes it easy to monitor CDK apps. Similarly, Cdk-wakeful takes that a step further, adding many additional services and provides easily configurable interfaces to automatically be notified by AWS System Manager Incident Manager, AWS Chatbot, or Amazon Simple Notification Service. By leveraging prebuilt solutions from the open-source community, you can focus on creating custom metrics and thresholds around your business logic. Platform Engineering teams can modify and extends 1open-source projects to help workload teams simplify their operations and emit health and status to centralized systems.

Accelerate New Project Startup with an Internal Developer Platform

An Internal Developer Platform (IDP) is built by platform engineering teams to build golden paths and enable developer self-service. These golden paths are expressed as a series of templates that the structure of a source control repository and files stored inside the repository. When the IDP uses these templates to create source code repositories, the resultant repository contains the following:

  • A getting-started tutorial (usually in a README.md)
  • Reference documentation
  • Skeleton source code
  • Dependency Management
  • CI/CD pipeline template
  • IaC template
  • Observability configuration

With CDK, the CI/CD pipeline, IaC template, and observability configuration can all be a part of a single CDK application.

Platform engineering teams build golden paths and expose them using tools like Backstage, Humanitec, or Port. When building golden paths, there are two common approaches to the underlying project structure. Some organizations choose the approach where their IaC code repository is separate from the application code. Others choose to include everything in one repository. There is a healthy tension between how much to place inside a golden path vs a reusable component. In both strategies, platform engineering teams can avoid code duplication by leveraging CDK. The approach your organization chooses will dictate how you organize your reusable components. Below, we will walk through both options and the implications on reusable constructs.

Option 1: Everything in one repository

In this approach, all the code is contained in one repository: infrastructure, application, configuration, and deployment. This approach enables builders to collaborate, build features, and innovate together quickly, which is why it is the recommended approach. For more details, refer to the Best practices documentation. For examples, see AWS Deployment Reference Architecture for Applications.

This approach works best in teams that are “value-stream aligned.” Value-stream aligned teams have development and operations capabilities within the same team. These teams are organized around solving problems for customers rather than technical capabilities. Within the project, teams can organize around logical units such as application tier (API, database, etc.) or business capabilities (order management, product catalog, delivery services, etc.). In organizations that are value stream aligned, larger, highly conventionalized reusable components are better. An extreme example of this type of constructs is a single construct that contains all the code for an entire microservice. In these teams, the cognitive load focuses on the customer problem, so reducing the complexity of developing applications is critical to success.

Option 2: Separated application code pipeline

In this alternative approach, you can decouple your application code from your infrastructure by storing them in separate repositories and having separate pipelines. Separating the pipelines often leads to siloes and less collaboration between workload builders, who shift focus to developing features, and infrastructure engineers, who limit their efforts to building the infrastructure on which those applications run.

This approach works best in teams that are “matrixed.” A matrix organization is structured around technical capabilities (development, operations, security, business, etc.). In these cases, more modular constructs work better than constructs that are highly conventionalized. Experts from each organization can use CDK constructs as mechanisms to share their expertise across the entire organization. Examples of these types of constructs are monitoring, alerting, or security constructs prebuilt with hooks to plug in to centralized monitoring.

Building a Community of Practice with Platform Engineering

Scaling any new technology within a large organization requires the creation and enablement of a community that fosters collaboration, establishes best practices, and stays up to date with the changes in the ecosystem. In order to enable the creation of these communities of practice within your organization, AWS supports multiple public communities centered around the creation of content to educate and enable CDK users. Members of your organization’s community of practice can connect with other CDK development teams around the world through these public AWS supported communities.

Communities of Practice

A Community of Practice (CoP) is a group of people with shared interest who come together to learn, collaborate and develop expertise in a specific domain through informal interactions and knowledge sharing. Within your organization, establishing communities of practice around CDK has been proven to enable mentorship, problem solving, and reusable assets. To get started, your platform engineering team – the creators of reusable constructs and builder tooling with CDK – become early content creators for the community of practice. This establishes a feedback loop where CDK creators publicize their achievements via the CoP and consumers can ask questions and provide direct guidance to creators. Once the CoP has sustainably expanded by the initial group that established it, the CoP can start to add hack-a-thons or game days within your organization, which can bring innovation and solve organization-wide challenges. Fully mature communities of practices own curated wikis or databases of knowledge. They use mechanisms such as townhalls, office hours, newsletters, and chat channels to keep the community up to date. In this way, CDK expertise is diffused across the organization. At AWS, this diffusion of expertise has led to teams other than platform engineering becoming creators of reusable constructs. By expanding who can create reusable constructs, we are able to accelerate our own innovation.

Communities

There is a growing community that supports CDK, with many different platforms available providing content, code, examples and meetups. CDK is currently maintained by AWS with support from the community on AWS CDK GitHub page where you can contribute to the platform, raise issues, see the backlog and join discussions with active community members.

CDK.dev is the community driven hub around the CDK ecosystem. This site brings together all the latest blogs, videos, and educational content. It also provides links to join the community Slack platform.

CDK Patterns houses an open source collection of AWS Serverless architecture patterns built with CDK for developers to use. These patterns are sources via AWS Community Builders / AWS Heroes.

Finally, AWS re:Post provides a question-and-answer portal for the community to resolve.

The AWS Community Builders program offers technical resources, education, and networking opportunities to AWS technical enthusiasts and emerging thought leaders who are passionate about sharing knowledge and connecting with the technical community.

Communities of practice can leverage AWS public communities like cdk.dev to fill gaps in knowledge. Townhalls can benefit from speakers from AWS Heroes or community builders, frequent contributors to GitHub or re:Post, or speakers from CDK Day. Newsletters can aggregate and summarize the latest news from across all AWS channels. Once your community of practice establishes CDK competencies, this collaboration can also be bidirectional. For example, experts in your organization’s community can become AWS Heroes. Success stories can be shared via CDK Day, guest blog posts, and you might even speak at one of our major events such as AWS Summits, AWS re:Invent, AWS re:Inforce, or AWS re:Mars.

Final Thoughts

As we’ve said throughout this blog, with CDK, Infrastructure is code. This has enabled a paradigm shift in the infrastructure management space. Today, we see many customers such as Liberty Mutual, Scenario, Checkmarx, and Registers of Scotland establishing mature ecosystems using CDK. With an active open-source community, an AWS dev team for long term support, and multiple platforms for knowledge sharing, your builders can quickly learn, build, and innovate. Due to successful pilots, many organizations adopt CDK, become more agile, and innovate faster. This is exactly what happened at Amazon, where CDK is the first choice for building new services.

Organizations often scale and reduce complexity through platform engineering. These teams build higher level constructs by applying best practices, and provide CI/CD pipelines to accelerate deployments. Your deployment is safer using unit testing on your infrastructure as code and through robust security controls to provide guidance to builders at every stage: from author to operate.

Finally, establishing a community enables your organization to build its own mature ecosystem. Through both internal and open-source communities your builders can connect, discover, and grow.

Photo of David Hessler

David Hessler

Prior to joining AWS, David spent a decade serving as a principal technologist and establishing Platform Engineering and SRE teams for the United States government. Since joining AWS in 2020, David has spent his time helping customers accelerate deployment speed and safety for some of AWS’s largest commercial and public sector customers. Today, as a part of the DevSecOps team within Global Services Security, he is building the next generation of DevSecOps tooling for AWS customers.

Amritha Shetty

Amritha Shetty

Amritha is a Solutions architect at AWS. She works with public sector customers to help migrate and modernize in the cloud. She loves helping citizens get more from public sector institutions through rapid innovation in the cloud. She brings over twelve years of software design and development experience and passionate about helping customers implement the next-generation development experience.

Photo of Chris Scudder

Chris Scudder

Chris is a Senior Solutions Architect with the UK Public Sector team. His primary focus is helping Public Sector customers adopt cloud technologies for their workloads, helping them streamline their development and operational processes. He has a background in application development and has created multiple Industry Solutions for UK Local Government. He has an interesting in Machine Learning and delivers AWS DeepRacer events alongside his day-to-day role.

Photo of Kumar Karra

Kumar Karra

Kumar Karra is a Senior Field Solutions Architect for AWS Small and Medium Business Customers. He has a strong background in designing and developing applications for small consumer facing customers to large mission critical applications for enterprises. He specialized in NextGen Developer Experience tools and enjoys helping customer shorten their time to value by guiding them on strategies to implement fast, repeatable, testable, and scalable tools and architectures.

Run Kinesis Agent on Amazon ECS

Post Syndicated from Buddhike de Silva original https://aws.amazon.com/blogs/big-data/run-kinesis-agent-on-amazon-ecs/

Kinesis Agent is a standalone Java software application that offers a straightforward way to collect and send data to Amazon Kinesis Data Streams and Amazon Kinesis Data Firehose. The agent continuously monitors a set of files and sends new data to the desired destination. The agent handles file rotation, checkpointing, and retry upon failures. It delivers all of your data in a reliable, timely, and simple manner. It also emits Amazon CloudWatch metrics to help you better monitor and troubleshoot the streaming process.

This post describes the steps to send data from a containerized application to Kinesis Data Firehose using Kinesis Agent. More specifically, we show how to run Kinesis Agent as a sidecar container for an application running in Amazon Elastic Container Service (Amazon ECS). After the data is in Kinesis Data Firehose, it can be sent to any supported destination, such as Amazon Simple Storage Service (Amazon S3).

In order to present the key points required for this setup, we assume that you are familiar with Amazon ECS and working with containers. We also avoid the implementation details and packaging process of our test data generation application, referred to as the producer.

Solution overview

As depicted in the following figure, we configure a Kinesis Agent container as a sidecar that can read files created by the producer container. In this instance, the producer and Kinesis Agent containers share data via a bind mount in Amazon ECS.

Solution design diagram

Prerequisites

You should satisfy the following prerequisites for the successful completion of this task:

With these prerequisites in place, you can begin next step to package a Kinesis Agent and your desired agent configuration as a container in your local development machine.

Create a Kinesis Agent configuration file

We use the Kinesis Agent configuration file to configure the source and destination, among other data transfer settings. The following code uses the minimal configuration required to read the contents of files matching /var/log/producer/*.log and publish them to a Kinesis Data Firehose delivery stream called kinesis-agent-demo:

{
    "firehose.endpoint": "firehose.ap-southeast-2.amazonaws.com",
    "flows": [
        {
            "deliveryStream": "kinesis-agent-demo",
            "filePattern": "/var/log/producer/*.log"
        }
    ]
}

Create a container image for Kinesis Agent

To deploy Kinesis Agent as a sidecar in Amazon ECS, you first have to package it as a container image. The container must have Kinesis Agent, which and find binaries, and the Kinesis Agent configuration file that you prepared earlier. Its entry point must be configured using the start-aws-kinesis-agent script. This command is installed when you run the yum install aws-kinesis-agent step. The resulting Dockerfile should look as follows:

FROM amazonlinux

RUN yum install -y aws-kinesis-agent which findutils
COPY agent.json /etc/aws-kinesis/agent.json

CMD ["start-aws-kinesis-agent"]

Run the docker build command to build this container:

docker build -t kinesis-agent .

After the image is built, it should be pushed to a container registry like Amazon ECR so that you can reference it in the next section.

Create an ECS task definition with Kinesis Agent and the application container

Now that you have Kinesis Agent packaged as a container image, you can use it in your ECS task definitions to run as sidecar. To do that, you create an ECS task definition with your application container (called producer) and Kinesis Agent container. All containers in a task definition are scheduled on the same container host and therefore can share resources such as bind mounts.

In the following sample container definition, we use a bind mount called logs_dir to share a directory between the producer container and kinesis-agent container.

You can use the following template as a starting point, but be sure to change taskRoleArn and executionRoleArn to valid IAM roles in your AWS account. In this instance, the IAM role used for taskRoleArn must have write permissions to Kinesis Data Firehose that you specified earlier in the agent.json file. Additionally, make sure that the ECR image paths and awslogs-region are modified as per your AWS account.

{
    "family": "kinesis-agent-demo",
    "taskRoleArn": "arn:aws:iam::111111111:role/kinesis-agent-demo-task-role",
    "executionRoleArn": "arn:aws:iam::111111111:role/kinesis-agent-test",
    "networkMode": "awsvpc",
    "containerDefinitions": [
        {
            "name": "producer",
            "image": "111111111.dkr.ecr.ap-southeast-2.amazonaws.com/producer:latest",
            "cpu": 1024,
            "memory": 2048,
            "essential": true,
            "command": [
                "-output",
                "/var/log/producer/test.log"
            ],
            "mountPoints": [
                {
                    "sourceVolume": "logs_dir",
                    "containerPath": "/var/log/producer",
                    "readOnly": false
                }
            ],
            "logConfiguration": {
                "logDriver": "awslogs",
                "options": {
                    "awslogs-create-group": "true",
                    "awslogs-group": "producer",
                    "awslogs-stream-prefix": "producer",
                    "awslogs-region": "ap-southeast-2"
                }
            }
        },
        {
            "name": "kinesis-agent",
            "image": "111111111.dkr.ecr.ap-southeast-2.amazonaws.com/kinesis-agent:latest",
            "cpu": 1024,
            "memory": 2048,
            "essential": true,
            "mountPoints": [
                {
                    "sourceVolume": "logs_dir",
                    "containerPath": "/var/log/producer",
                    "readOnly": true
                }
            ],
            "logConfiguration": {
                "logDriver": "awslogs",
                "options": {
                    "awslogs-create-group": "true",
                    "awslogs-group": "kinesis-agent",
                    "awslogs-stream-prefix": "kinesis-agent",
                    "awslogs-region": "ap-southeast-2"
                }
            }
        }
    ],
    "volumes": [
        {
            "name": "logs_dir"
        }
    ],
    "requiresCompatibilities": [
        "FARGATE"
    ],
    "cpu": "2048",
    "memory": "4096"
}

Register the task definition with the following command:

aws ecs register-task-definition --cli-input-json file://./task-definition.json

Run a new ECS task

Finally, you can run a new ECS task using the task definition you just created using the aws ecs run-task command. When the task is started, you should be able to see two containers running under that task on the Amazon ECS console.

Amazon ECS console screenshot

Conclusion

This post showed how straightforward it is to run Kinesis Agent in a containerized environment. Although we used Amazon ECS as our container orchestration service in this post, you can use a Kinesis Agent container in other environments such as Amazon Elastic Kubernetes Service (Amazon EKS).

To learn more about using Kinesis Agent, refer to Writing to Amazon Kinesis Data Streams Using Kinesis Agent. For more information about Amazon ECS, refer to the Amazon ECS Developer Guide.


About the Author

Buddhike de Silva is a Senior Specialist Solutions Architect at Amazon Web Services. Buddhike helps customers run large scale streaming analytics workloads on AWS and make the best out of their cloud journey.

Best Practices to help secure your container image build pipeline by using AWS Signer

Post Syndicated from Jorge Castillo original https://aws.amazon.com/blogs/security/best-practices-to-help-secure-your-container-image-build-pipeline-by-using-aws-signer/

AWS Signer is a fully managed code-signing service to help ensure the trust and integrity of your code. It helps you verify that the code comes from a trusted source and that an unauthorized party has not accessed it. AWS Signer manages code signing certificates and public and private keys, which can reduce the overhead of your public key infrastructure (PKI) management. It also provides a set of features to simplify lifecycle management of your keys and certificates so that you can focus on signing and verifying your code.

In June 2023, AWS announced Container Image Signing with AWS Signer and Amazon EKS, a new capability that gives you native AWS support for signing and verifying container images stored in Amazon Elastic Container Registry (Amazon ECR).

Containers and AWS Lambda functions are popular serverless compute solutions for applications built on the cloud. By using AWS Signer, you can verify that the software running in these workloads originates from a trusted source.

In this blog post, you will learn about the benefits of code signing for software security, governance, and compliance needs. Flexible continuous integration and continuous delivery (CI/CD) integration, management of signing identities, and native integration with other AWS services can help you simplify code security through automation.

Background

Code signing is an important part of the software supply chain. It helps ensure that the code is unaltered and comes from an approved source.

To automate software development workflows, organizations often implement a CI/CD pipeline to push, test, and deploy code effectively. You can integrate code signing into the workflow to help prevent untrusted code from being deployed, as shown in Figure 1. Code signing in the pipeline can provide you with different types of information, depending on how you decide to use the functionality. For example, you can integrate code signing into the build stage to attest that the code was scanned for vulnerabilities, had its software bill of materials (SBOM) approved internally, and underwent unit and integration testing. You can also use code signing to verify who has pushed or published the code, such as a developer, team, or organization. You can verify each of these steps separately by including multiple signing stages in the pipeline. For more information on the value provided by container image signing, see Cryptographic Signing for Containers.

Figure 1: Security IN the pipeline

Figure 1: Security IN the pipeline

In the following section, we will walk you through a simple implementation of image signing and its verification for Amazon Elastic Kubernetes Service (Amazon EKS) deployment. The signature attests that the container image went through the pipeline and came from a trusted source. You can use this process in more complex scenarios by adding multiple AWS CodeBuild code signing stages that make use of various AWS Signer signing profiles.

Services and tools

In this section, we discuss the various AWS services and third-party tools that you need for this solution.

CI/CD services

For the CI/CD pipeline, you will use the following AWS services:

  • AWS CodePipeline — a fully managed continuous delivery service that you can use to automate your release pipelines for fast and reliable application and infrastructure updates.
  • AWS CodeCommit — a fully managed source control service that hosts secure Git-based repositories.
  • AWS Signer — a fully managed code-signing service that you can use to help ensure the trust and integrity of your code.
  • AWS CodeBuild — A fully managed continuous integration service that compiles source code, runs tests, and produces software packages that are ready to deploy.

Container services

You will use the following AWS services for containers for this walkthrough:

  • Amazon EKS — a managed Kubernetes service to run Kubernetes in the AWS Cloud and on-premises data centers.
  • Amazon ECR — a fully managed container registry for high-performance hosting, so that you can reliably deploy application images and artifacts anywhere.

Verification tools

The following are publicly available sign verification tools that we integrated into the pipeline for this post, but you could integrate other tools that meet your specific requirements.

  • Notation — A publicly available Notary project within the Cloud Native Computing Foundation (CNCF). With contributions from AWS and others, Notary is an open standard and client implementation that allows for vendor-specific plugins for key management and other integrations. AWS Signer manages signing keys, key rotation, and PKI management for you, and is integrated with Notation through a curated plugin that provides a simple client-based workflow.
  • Kyverno — A publicly available policy engine that is designed for Kubernetes.

Solution overview

Figure 2: Solution architecture

Figure 2: Solution architecture

Here’s how the solution works, as shown in Figure 2:

  1. Developers push Dockerfiles and application code to CodeCommit. Each push to CodeCommit starts a pipeline hosted on CodePipeline.
  2. CodeBuild packages the build, containerizes the application, and stores the image in the ECR registry.
  3. CodeBuild retrieves a specific version of the image that was previously pushed to Amazon ECR. AWS Signer and Notation sign the image by using the signing profile established previously, as shown in more detail in Figure 3.
    Figure 3: Signing images described

    Figure 3: Signing images described

  4. AWS Signer and Notation verify the signed image version and then deploy it to an Amazon EKS cluster.

    If the image has not previously been signed correctly, the CodeBuild log displays an output similar to the following:

    Error: signature verification failed: no signature is associated with "<AWS_ACCOUNT_ID>.dkr.ecr.<AWS_REGION>.amazonaws.com/hello-server@<DIGEST>" , make sure the artifact was signed successfully

    If there is a signature mismatch, the CodeBuild log displays an output similar to the following:

    Error: signature verification failed for all the signatures associated with <AWS_ACCOUNT_ID>.dkr.ecr.<AWS_REGION>.amazonaws.com/hello-server@<DIGEST>

  5. Kyverno verifies the container image signature for use in the Amazon EKS cluster.

    Figure 4 shows steps 4 and 5 in more detail.

    Figure 4: Verification of image signature for Kubernetes

    Figure 4: Verification of image signature for Kubernetes

Prerequisites

Before getting started, make sure that you have the following prerequisites in place:

  • An Amazon EKS cluster provisioned.
  • An Amazon ECR repository for your container images.
  • A CodeCommit repository with your application code. For more information, see Create an AWS CodeCommit repository.
  • A CodePipeline pipeline deployed with the CodeCommit repository as the code source and four CodeBuild stages: Build, ApplicationSigning, ApplicationDeployment, and VerifyContainerSign. The CI/CD pipeline should look like that in Figure 5.
    Figure 5: CI/CD pipeline with CodePipeline

    Figure 5: CI/CD pipeline with CodePipeline

Walkthrough

You can create a signing profile by using the AWS Command Line Interface (AWS CLI), AWS Management Console or the AWS Signer API. In this section, we’ll walk you through how to sign the image by using the AWS CLI.

To sign the image (AWS CLI)

  1. Create a signing profile for each identity.
    # Create an AWS Signer signing profile with default validity period
    $ aws signer put-signing-profile \
        --profile-name build_signer \
        --platform-id Notation-OCI-SHA384-ECDSA

  2. Sign the image from the CodeBuild build—your buildspec.yaml configuration file should look like the following:
    version: 0.2
    
    phases:
      pre_build:
        commands:
          - aws ecr get-login-password --region $AWS_REGION | docker login --username AWS --password-stdin $AWS_ACCOUNT_ID.dkr.ecr.us-east-1.amazonaws.com
          - REPOSITORY_URI=$AWS_ACCOUNT_ID.dkr.ecr. $AWS_REGION.amazonaws.com/hello-server
          - COMMIT_HASH=$(echo $CODEBUILD_RESOLVED_SOURCE_VERSION | cut -c 1-7)
          - IMAGE_TAG=${COMMIT_HASH:=latest}
          - DIGEST=$(docker manifest inspect $AWS_ACCOUNT_ID.dkr.ecr. $AWS_REGION.amazonaws.com/hello-server:$IMAGE_TAG -v | jq -r '.Descriptor.digest')
          - echo $DIGEST
          
          - wget https://d2hvyiie56hcat.cloudfront.net/linux/amd64/installer/rpm/latest/aws-signer-notation-cli_amd64.rpm
          - sudo rpm -U aws-signer-notation-cli_amd64.rpm
          - notation version
          - notation plugin ls
      build:
        commands:
          - notation sign $REPOSITORY_URI@$DIGEST --plugin com.amazonaws.signer.notation.plugin --id arn:aws:signer: $AWS_REGION:$AWS_ACCOUNT_ID:/signing-profiles/notation_container_signing
          - notation inspect $AWS_ACCOUNT_ID.dkr.ecr. $AWS_REGION.amazonaws.com/hello-server@$DIGEST
          - notation verify $AWS_ACCOUNT_ID.dkr.ecr. $AWS_REGION.amazonaws.com/hello-server@$DIGEST
      post_build:
        commands:
          - printf '[{"name":"hello-server","imageUri":"%s"}]' $REPOSITORY_URI:$IMAGE_TAG > imagedefinitions.json
    artifacts:
        files: imagedefinitions.json

    The commands in the buildspec.yaml configuration file do the following:

    1. Sign you in to Amazon ECR to work with the Docker images.
    2. Reference the specific image that will be signed by using the commit hash (or another versioning strategy that your organization uses). This gets the digest.
    3. Sign the container image by using the notation sign command. This command uses the container image digest, instead of the image tag.
    4. Install the Notation CLI. In this example, you use the installer for Linux. For a list of installers for various operating systems, see the AWS Signer Developer Guide,
    5. Sign the image by using the notation sign command.
    6. Inspect the signed image to make sure that it was signed successfully by using the notation inspect command.
    7. To verify the signed image, use the notation verify command. The output should look similar to the following:
      Successfully verified signature for <AWS_ACCOUNT_ID>.dkr.ecr.<AWS_REGION>.amazonaws.com/hello-server@<DIGEST>

  3. (Optional) For troubleshooting, print the notation policy from the pipeline itself to check that it’s working as expected by running the notation policy show command:
    notation policy show

    For this, include the command in the pre_build phase after the notation version command in the buildspec.yaml configuration file.

    After the notation policy show command runs, CodeBuild logs should display an output similar to the following:

    {
      "version": "1.0",
      "trustPolicies": [
        {
          "name": "aws-signer-tp",
          "registryScopes": [
          "<AWS_ACCOUNT_ID>.dkr.ecr.<AWS_REGION>.amazonaws.com/hello-server"
          ],
          "signatureVerification": {
            "level": "strict"
          },
          "trustStores": [
            "signingAuthority:aws-signer-ts"
          ],
          "trustedIdentities": [
            "arn:aws:signer:<AWS_REGION>:<AWS_ACCOUNT_ID>:/signing-profiles/notation_test"
          ]
        }
      ]
    }

  4. To verify the image in Kubernetes, set up both Kyverno and the Kyverno-notation-AWS Signer in your EKS cluster. To get started with Kyverno and the Kyverno-notation-AWS Signer solution, see the installation instructions.
  5. After you install Kyverno and Kyverno-notation-AWS Signer, verify that the controller is running—the STATUS should show Running:
    $ kubectl get pods -n kyverno-notation-aws -w
    
    NAME                                    READY   STATUS    RESTARTS   AGE
    kyverno-notation-aws-75b7ddbcfc-kxwjh   1/1     Running   0          6h58m

  6. Configure the CodeBuild buildspec.yaml configuration file to verify that the images deployed in the cluster have been previously signed. You can use the following code to configure the buildspec.yaml file.
    version: 0.2
    
    phases:
      pre_build:
        commands:
          - echo Logging in to Amazon ECR...
          - aws --version
          - REPOSITORY_URI=${REPO_ECR}
          - COMMIT_HASH=$(echo $CODEBUILD_RESOLVED_SOURCE_VERSION | cut -c 1-7)
          - IMAGE_TAG=${COMMIT_HASH:=latest}
          - curl -LO "https://dl.k8s.io/release/$(curl -L -s https://dl.k8s.io/release/stable.txt)/bin/linux/amd64/kubectl"
          - curl -LO "https://dl.k8s.io/release/$(curl -L -s https://dl.k8s.io/release/stable.txt)/bin/linux/amd64/kubectl.sha256"
          - echo "$(cat kubectl.sha256)  kubectl" | sha256sum --check
          — chmod +x kubectl
          - mv ./kubectl /usr/local/bin/kubectl
          - kubectl version --client
      build:
        commands:
          - echo Build started on `date`
          - aws eks update-kubeconfig -—name ${EKS_NAME} —-region ${AWS_DEFAULT_REGION}
          - echo Deploying Application
          - sed -i '/image:\ image/image:\ '\"${REPOSITORY_URI}:${IMAGE_TAG}\"'/g' deployment.yaml
          - kubectl apply -f deployment.yaml 
          - KYVERNO_NOTATION_POD=$(kubectl get pods --no-headers -o custom-columns=":metadata.name" -n kyverno-notation-aws)
          - STATUS=$(kubectl logs --tail=1 kyverno-notation-aws-75b7ddbcfc-kxwjh -n kyverno-notation-aws | grep $IMAGE_TAG | grep ERROR)
          - |
            if [[ $STATUS ]]; then
              echo "There is an error"
              exit 1
            else
              echo "No Error"
            fi
      post_build:
        commands:
          - printf '[{"name":"hello-server","imageUri":"%s"}]' $REPOSITORY_URI:$IMAGE_TAG > imagedefinitions.json
    artifacts:
        files: imagedefinitions.json

    The commands in the buildspec.yaml configuration file do the following:

    1. Set up the environment variables, such as the ECR repository URI and the Commit hash, to build the image tag. The kubectl tool will use this later to reference the container image that will be deployed with the Kubernetes objects.
    2. Use kubectl to connect to the EKS cluster and insert the container image reference in the deployment.yaml file.
    3. After the container is deployed, you can observe the kyverno-notation-aws controller and access its logs. You can check if the deployed image is signed. If the logs contain an error, stop the pipeline run with an error code, do a rollback to a previous version, or delete the deployment if you detect that the image isn’t signed.

Decommission the AWS resources

If you no longer need the resources that you provisioned for this post, complete the following steps to delete them.

To clean up the resources

  1. Delete the EKS cluster and delete the ECR image.
  2. Delete the IAM roles and policies that you used for the configuration of IAM roles for service accounts.
  3. Revoke the AWS Signer signing profile that you created and used for the signing process by running the following command in the AWS CLI:
    $ aws signer revoke-signing-profile

  4. Delete signatures from the Amazon ECR repository. Make sure to replace <AWS_ACCOUNT_ID> and <AWS_REGION> with your own information.
    # Use oras CLI, with Amazon ECR Docker Credential Helper, to delete signature
    $ oras manifest delete <AWS_ACCOUNT_ID>.dkr.ecr.<AWS_REGION>.amazonaws.com/pause@sha256:ca78e5f730f9a789ef8c63bb55275ac12dfb9e8099e6a0a64375d8a95ed501c4

Note: Using the ORAS project’s oras client, you can delete signatures and other reference type artifacts. It implements deletion by first removing the reference from an index, and then deleting the manifest.

Conclusion

In this post, you learned how to implement container image signing in a CI/CD pipeline by using AWS services such as CodePipeline, CodeBuild, Amazon ECR, and AWS Signer along with publicly available tools such as Notary and Kyverno. By implementing mandatory image signing in your pipelines, you can confirm that only validated and authorized container images are deployed to production. Automating the signing process and signature verification is vital to help securely deploy containers at scale. You also learned how to verify signed images both during deployment and at runtime in Kubernetes. This post provides valuable insights for anyone looking to add image signing capabilities to their CI/CD pipelines on AWS to provide supply chain security assurances. The combination of AWS managed services and publicly available tools provides a robust implementation.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Jorge Castillo

Jorge Castillo

Jorge is a Solutions Architect at AWS for the public sector based in Santiago, Chile. He focuses on security and compliance and works with many government agencies.

Joseph Rodríguez

Joseph Rodríguez

Joseph is a Solutions Architect at AWS for the public sector based in Chile. Joseph has collaborated with multiple public sector institutions on cloud technology adoption, with a focus on containers. He previously worked as a Software Architect at financial services institutions.

Monika Vu Minh

Monika Vu Minh

Monika is a ProServe Security Consultant at AWS based in London. She works with financial services customers to help them follow security best practices on AWS. In her free time, she likes painting, cooking, and travelling.

New Amazon CloudWatch log class to cost-effectively scale your AWS Glue workloads

Post Syndicated from Noritaka Sekiyama original https://aws.amazon.com/blogs/big-data/new-amazon-cloudwatch-log-class-to-cost-effectively-scale-your-aws-glue-workloads/

AWS Glue is a serverless data integration service that makes it easier to discover, prepare, and combine data for analytics, machine learning (ML), and application development. You can use AWS Glue to create, run, and monitor data integration and ETL (extract, transform, and load) pipelines and catalog your assets across multiple data stores.

One of the most common questions we get from customers is how to effectively optimize costs on AWS Glue. Over the years, we have built multiple features and tools to help customers manage their AWS Glue costs. For example, AWS Glue Auto Scaling and AWS Glue Flex can help you reduce the compute cost associated with processing your data. AWS Glue interactive sessions and notebooks can help you reduce the cost of developing your ETL jobs. For more information about cost-saving best practices, refer to Monitor and optimize cost on AWS Glue for Apache Spark. Additionally, to understand data transfer costs, refer to the Cost Optimization Pillar defined in AWS Well-Architected Framework. For data storage, you can apply general best practices defined for each data source. For a cost optimization strategy using Amazon Simple Storage Service (Amazon S3), refer to Optimizing storage costs using Amazon S3.

In this post, we tackle the remaining piece—the cost of logs written by AWS Glue.

Before we get into the cost analysis of logs, let’s understand the reasons to enable logging for your AWS Glue job and the current options available. When you start an AWS Glue job, it sends the real-time logging information to Amazon CloudWatch (every 5 seconds and before each executor stops) during the Spark application starts running. You can view the logs on the AWS Glue console or the CloudWatch console dashboard. These logs provide you with insights into your job runs and help you optimize and troubleshoot your AWS Glue jobs. AWS Glue offers a variety of filters and settings to reduce the verbosity of your logs. As the number of job runs increases, so does the volume of logs generated.

To optimize CloudWatch Logs costs, AWS recently announced a new log class for infrequently accessed logs called Amazon CloudWatch Logs Infrequent Access (Logs IA). This new log class offers a tailored set of capabilities at a lower cost for infrequently accessed logs, enabling you to consolidate all your logs in one place in a cost-effective manner. This class provides a more cost-effective option for ingesting logs that only need to be accessed occasionally for auditing or debugging purposes.

In this post, we explain what the Logs IA class is, how it can help reduce costs compared to the standard log class, and how to configure your AWS Glue resources to use this new log class. By routing logs to Logs IA, you can achieve significant savings in your CloudWatch Logs spend without sacrificing access to important debugging information when you need it.

CloudWatch log groups used by AWS Glue job continuous logging

When continuous logging is enabled, AWS Glue for Apache Spark writes Spark driver/executor logs and progress bar information into the following log group:

/aws-glue/jobs/logs-v2

If a security configuration is enabled for CloudWatch logs, AWS Glue for Apache Spark will create a log group named as follows for continuous logs:

<Log-Group-Name>-<Security-Configuration-Name>

The default and custom log groups will be as follows:

  • The default continuous log group will be /aws-glue/jobs/logs-v2-<Security-Configuration-Name>
  • The custom continuous log group will be <custom-log-group-name>-<Security-Configuration-Name>

You can provide a custom log group name through the job parameter –continuous-log-logGroup.

Getting started with the new Infrequent Access log class for AWS Glue workload

To gain the benefits from Logs IA for your AWS Glue workloads, you need to complete the following two steps:

  1. Create a new log group using the new Log IA class.
  2. Configure your AWS Glue job to point to the new log group

Complete the following steps to create a new log group using the new Infrequent Access log class:

  1. On the CloudWatch console, choose Log groups under Logs in the navigation pane.
  2. Choose Create log group.
  3. For Log group name, enter /aws-glue/jobs/logs-v2-infrequent-access.
  4. For Log class, choose Infrequent Access.
  5. Choose Create.

Complete the following steps to configure your AWS Glue job to point to the new log group:

  1. On the AWS Glue console, choose ETL jobs in the navigation pane.
  2. Choose your job.
  3. On the Job details tab, choose Add new parameter under Job parameters.
  4. For Key, enter --continuous-log-logGroup.
  5. For Value, enter /aws-glue/jobs/logs-v2-infrequent-access.
  6. Choose Save.
  7. Choose Run to trigger the job.

New log events are written into the new log group.

View the logs with the Infrequent Access log class

Now you’re ready to view the logs with the Infrequent Access log class. Open the log group /aws-glue/jobs/logs-v2-infrequent-access on the CloudWatch console.

When you choose one of the log streams, you will notice that it redirects you to the CloudWatch console Logs Insight page with a pre-configured default command and your log stream selected by default. By choosing Run query, you can view the actual log events on the Logs Insights page.

Considerations

Keep in mind the following considerations:

  • You cannot change the log class of a log group after it’s created. You need to create a new log group to configure the Infrequent Access class.
  • The Logs IA class offers a subset of CloudWatch Logs capabilities, including managed ingestion, storage, cross-account log analytics, and encryption with a lower ingestion price per GB. For example, you can’t view log events through the standard CloudWatch Logs console. To learn more about the features offered across both log classes, refer to Log Classes.

Conclusion

This post provided step-by-step instructions to guide you through enabling Logs IA for your AWS Glue job logs. If your AWS Glue ETL jobs generate large volumes of log data that makes it a challenge as you scale your applications, the best practices demonstrated in this post can help you cost-effectively scale while centralizing all your logs in CloudWatch Logs. Start using the Infrequent Access class with your AWS Glue workloads today and enjoy the cost benefits.


About the Authors

Noritaka Sekiyama is a Principal Big Data Architect on the AWS Glue team. He works based in Tokyo, Japan. He is responsible for building software artifacts to help customers. In his spare time, he enjoys cycling on his road bike.

Abeetha Bala is a Senior Product Manager for Amazon CloudWatch, primarily focused on logs. Being customer obsessed, she solves observability challenges through innovative and cost-effective ways.

Kinshuk Pahare is a leader in AWS Glue’s product management team. He drives efforts on the platform, developer experience, and big data processing frameworks like Apache Spark, Ray, and Python Shell.

Getting started with Projen and AWS CDK

Post Syndicated from Michael Tran original https://aws.amazon.com/blogs/devops/getting-started-with-projen-and-aws-cdk/

In the modern world of cloud computing, Infrastructure as Code (IaC) has become a vital practice for deploying and managing cloud resources. AWS Cloud Development Kit (AWS CDK) is a popular open-source framework that allows developers to define cloud resources using familiar programming languages. A related open source tool called Projen is a powerful project generator that simplifies the management of complex software configurations. In this post, we’ll explore how to get started with Projen and AWS CDK, and discuss the pros and cons of using Projen.

What is Projen?

Building modern and high quality software requires a large number of tools and configuration files to handle tasks like linting, testing, and automating releases. Each tool has its own configuration interface, such as JSON or YAML, and a unique syntax, increasing maintenance complexity.

When starting a new project, you rarely start from scratch, but more often use a scaffolding tool (for instance, create-react-app) to generate a new project structure. A large amount of configuration is created on your behalf, and you get the ownership of those files. Moreover, there is a high number of project generation tools, with new ones created almost everyday.

Projen is a project generator that helps developers to efficiently manage project configuration files and build high quality software. It allows you to define your project structure and configuration in code, making it easier to maintain and share across different environments and projects.

Out of the box, Projen supports multiple project types like AWS CDK construct libraries, react applications, Java projects, and Python projects. New project types can be added by contributors, and projects can be developed in multiple languages. Projen uses the jsii library, which allows us to write APIs once and generate libraries in several languages. Moreover, Projen provides a single interface, the projenrc file, to manage the configuration of your entire project!

The diagram below provides an overview of the deployment process of AWS cloud resources using Projen:

Projen Overview of Deployment process of AWS Resources


  1. In this example, Projen can be used to generate a new project, for instance, a new CDK Typescript application.
  2. Developers define their infrastructure and application code using AWS CDK resources. To modify the project configuration, developers use the projenrc file instead of directly editing files like package.json.
  3. The project is synthesized to produce an AWS CloudFormation template.
  4. The CloudFormation template is deployed in a AWS account, and provisions AWS cloud resources.

Projen_Diagram
Diagram 1 – Projen packaged features: Projen helps gets your project started and allows you to focus on coding instead of worrying about the other project variables. It comes out of the box with linting, unit test and code coverage, and a number of Github actions for release and versioning and dependency management.

Pros and Cons of using Projen

Pros

  1. Consistency: Projen ensures consistency across different projects by allowing you to define standard project templates. You don’t need to use different project generators, only Projen.
  2. Version Control: Since project configuration is defined in code, it can be version-controlled, making it easier to track changes and collaborate with others.
  3. Extensibility: Projen supports various plugins and extensions, allowing you to customize the project configuration to fit your specific needs.
  4. Integration with AWS CDK: Projen provides seamless integration with AWS CDK, simplifying the process of defining and deploying cloud resources.
  5. Polyglot CDK constructs library: Build once, run in multiple runtimes. Projen can convert and publish a CDK Construct developed in TypeScript to Java (Maven) and Python (PYPI) with JSII support.
  6. API Documentation : Generate API documentation from the comments, if you are building a CDK construct

Cons

  1. Microsoft Windows support. There are a number of open issues about Projen not completely working with the Windows environment (https://github.com/projen/projen/issues/2427 and https://github.com/projen/projen/issues/498).
  2. The framework, Projen, is very opinionated with a lot of assumptions on architecture, best practices and conventions.
  3. Projen is still not GA, with the version at the time of this writing at v0.77.5.

Walkthrough

Step 1: Set up prerequisites

  • An AWS account
  • Download and install Node
  • Install yarn
  • AWS CLI : configure your credentials
  • Deploying stacks with the AWS CDK requires dedicated Amazon S3 buckets and other containers to be available to AWS CloudFormation during deployment (More information).

Note: Projen doesn’t need to be installed globally. You will be using npx to run Projen which takes care of all required setup steps. npx is a tool for running npm packages that:

  • live inside of a local node_modules folder
  • are not installed globally.

npx comes bundled with npm version 5.2+

Step 2: Create a New Projen Project

You can create a new Projen project using the following command:

mkdir test_project && cd test_project
npx projen new awscdk-app-ts

This command creates a new TypeScript project with AWS CDK support. The exhaustive list of supported project types is available through the official documentation: Projen.io, or by running the npx projen new command without a project type. It also supports npx projen new awscdk-construct to create a reusable construct which can then be published to other package managers.

The created project structure should be as follows:

test_project
| .github/
| .projen/
| src/
| test/
| .eslintrc
| .gitattributes
| .gitignore
| .mergify.yml
| .npmignore
| .projenrc.js
| cdk.json
| LICENSE
| package.json
| README.md
| tsconfig.dev.json
| yarn.lock

Projen generated a new project including:

  • Initialization of an empty git repository, with the associated GitHub workflow files to build and upgrade the project. The release workflow can be customized with projen tasks.
  • .projenrc.js is the main configuration file for project
  • tasks.json file for integration with Visual Studio Code
  • src folder containing an empty CDK stack
  • License and README files
  • A projen configuration file: projenrc.js
  • package.json contains functional metadata about the project like name, versions and dependencies.
  • .gitignore, .gitattributes file to manage your files with git.
  • .eslintrc identifying and reporting patterns on javascript.
  • .npmignore to keep files out of package manager.
  • .mergify.yml for managing the pull requests.
  • tsconfig.json configure the compiler options

Most of the generated files include a disclaimer:

# ~~ Generated by projen. To modify, edit .projenrc.js and run "npx projen".

Projen’s power lies in its single configuration file, .projenrc.js. By editing this file, you can manage your project’s lint rules, dependencies, .gitignore, and more. Projen will propagate your changes across all generated files, simplifying and unifying dependency management across your projects.

Projen generated files are considered implementation details and are not meant to be edited manually. If you do make manual changes, they will be overwritten the next time you run npx projen.

To edit your project configuration, simply edit .projenrc.js and then run npx projen to synthesize again. For more information on the Projen API, please see the documentation: http://projen.io/api/API.html.

Projen uses the projenrc.js file’s configuration to instantiate a new AwsCdkTypeScriptApp with some basic metadata: the project name, CDK version and the default release branch. Additional APIs are available for this project type to customize it (for instance, add runtime dependencies).

Let’s try to modify a property and see how Projen reacts. As an example, let’s update the project name in projenrc.js :

name: 'test_project_2',

and then run the npx projen command:

npx projen

Once done, you can see that the project name was updated in the package.json file.

Step 3: Define AWS CDK Resources

Inside your Projen project, you can define AWS CDK resources using familiar programming languages like TypeScript. Here’s an example of defining an Amazon Simple Storage Service (Amazon S3) bucket:

1. Navigate to your main.ts file in the src/ directory
2. Modify the imports at the top of the file as follow:

import { App, CfnOutput, Stack, StackProps } from 'aws-cdk-lib';
import * as s3 from 'aws-cdk-lib/aws-s3';
import { Construct } from 'constructs';

1. Replace line 9 “// define resources here…” with the code below:

const bucket = new s3.Bucket(this, 'MyBucket', {
  versioned: true,
});

new CfnOutput(this, 'TestBucket', { value: bucket.bucketArn });

Step 4: Synthesize and Deploy

Next we will bootstrap our application. Run the following in a terminal:

$ npx cdk bootstrap

Once you’ve defined your resources, you can synthesize a cloud assembly, which includes a CloudFormation template (or many depending on the application) using:

$ npx projen build

npx projen build will perform several actions:

  1. Build the application
  2. Synthesize the CloudFormation template
  3. Run tests and linter

The synth() method of Projen performs the actual synthesizing (and updating) of all configuration files managed by Projen. This is achieved by deleting all Projen-managed files (if there are any), and then re-synthesizing them based on the latest configuration specified by the user.

You can find an exhaustive list of the available npx projen commands in .projen/tasks.json. You can also use the projen API project.addTask to add a new task to perform any custom action you need ! Tasks are a project-level feature to define a project command system backed by shell scripts.

Deploy the CDK application:

$ npx projen deploy

Projen will use the cdk deploy command to deploy the CloudFormation stack in the configured AWS account by creating and executing a change set based on the template generated by CDK synthesis. The output of the step above should look as follow:

deploy | cdk deploy

✨ Synthesis time: 3.28s

toto-dev: start: Building 387a3a724050aec67aa083b74c69485b08a876f038078ec7ea1018c7131f4605:263905523351-us-east-1
toto-dev: success: Built 387a3a724050aec67aa083b74c69485b08a876f038078ec7ea1018c7131f4605:263905523351-us-east-1
toto-dev: start: Publishing 387a3a724050aec67aa083b74c69485b08a876f038078ec7ea1018c7131f4605:263905523351-us-east-1
toto-dev: success: Published 387a3a724050aec67aa083b74c69485b08a876f038078ec7ea1018c7131f4605:263905523351-us-east-1
toto-dev: deploying... [1/1]
toto-dev: creating CloudFormation changeset...

✅ testproject-dev

✨ Deployment time: 33.48s

Outputs:
testproject-dev.TestBucket = arn:aws:s3:::testproject-dev-mybucketf68f3ff0-1xy2f0vk0ve4r
Stack ARN:
arn:aws:cloudformation:us-east-1:263905523351:stack/testproject-dev/007e7b20-48df-11ee-b38d-0aa3a92c162d

✨ Total time: 36.76s

The application was successfully deployed in the configured AWS account! Also, the Amazon Resource Name (ARN) of the S3 bucket created is available through the CloudFormation stack Outputs tab, and displayed in your terminal under the ‘Outputs’ section.

Clean up

Delete CloudFormation Stack

To clean up the resources created in this section of the workshop, navigate to the CloudFormation console and delete the stack created. You can also perform the same task programmatically:

$ npx projen destroy

Which should produce the following output:

destroy | cdk destroy
Are you sure you want to delete: testproject-dev (y/n)? y
testproject-dev: destroying... [1/1]

✅ testproject-dev: destroyed

Delete S3 Buckets

The S3 bucket will not be deleted since its retention policy was set to RETAIN. Navigate to the S3 console and delete the created bucket. If you added files to that bucket, you will need to empty it before deletion. See the Deleting a bucket documentation for more information.

Conclusion

Projen and AWS CDK together provide a powerful combination for managing cloud resources and project configuration. By leveraging Projen, you can ensure consistency, version control, and extensibility across your projects. The integration with AWS CDK allows you to define and deploy cloud resources using familiar programming languages, making the entire process more developer-friendly.

Whether you’re a seasoned cloud developer or just getting started, Projen and AWS CDK offer a streamlined approach to cloud resource management. Give it a try and experience the benefits of Infrastructure as Code with the flexibility and power of modern development tools.

Alain Krok

Alain Krok is a Senior Solutions Architect with a passion for emerging technologies. His past experience includes designing and implementing IIoT solutions for the oil and gas industry and working on robotics projects. He enjoys pushing the limits and indulging in extreme sports when he is not designing software.


Dinesh Sajwan

Dinesh Sajwan is a Senior Solutions Architect. His passion for emerging technologies allows him to stay on the cutting edge and identify new ways to apply the latest advancements to solve even the most complex business problems. His diverse expertise and enthusiasm for both technology and adventure position him as a uniquely creative problem-solver.

Michael Tran

Michael Tran is a Sr. Solutions Architect with Prototyping Acceleration team at Amazon Web Services. He provides technical guidance and helps customers innovate by showing the art of the possible on AWS. He specializes in building prototypes in the AI/ML space. You can contact him @Mike_Trann on Twitter.

Governance at scale: Enforce permissions and compliance by using policy as code

Post Syndicated from Roland Odorfer original https://aws.amazon.com/blogs/security/governance-at-scale-enforce-permissions-and-compliance-by-using-policy-as-code/

AWS Identity and Access Management (IAM) policies are at the core of access control on AWS. They enable the bundling of permissions, helping to provide effective and modular access control for AWS services. Service control policies (SCPs) complement IAM policies by helping organizations enforce permission guardrails at scale across their AWS accounts.

The use of access control policies isn’t limited to AWS resources. Customer applications running on AWS infrastructure can also use policies to help control user access. This often involves implementing custom authorization logic in the program code itself, which can complicate audits and policy changes.

To address this, AWS developed Amazon Verified Permissions, which helps implement fine-grained authorizations and permissions management for customer applications. This service uses Cedar, an open-source policy language, to define permissions separately from application code.

In addition to access control, you can also use policies to help monitor your organization’s individual governance rules for security, operations and compliance. One example of such a rule is the regular rotation of cryptographic keys to help reduce the impact in the event of a key leak.

However, manually checking and enforcing such rules is complex and doesn’t scale, particularly in fast-growing IT organizations. Therefore, organizations should aim for an automated implementation of such rules. In this blog post, I will show you how to use policy as code to help you govern your AWS landscape.

Policy as code

Similar to infrastructure as code (IaC), policy as code is an approach in which you treat policies like regular program code. You define policies in the form of structured text files (policy documents), which policy engines can automatically evaluate.

The main advantage of this approach is the ability to automate key governance tasks, such as policy deployment, enforcement, and auditing. By storing policy documents in a central repository, you can use versioning, simplify audits, and track policy changes. Furthermore, you can subject new policies to automated testing through integration into a continuous integration and continuous delivery (CI/CD) pipeline. Policy as code thus forms one of the key pillars of a modern automated IT governance strategy.

The following sections describe how you can combine different AWS services and functions to integrate policy as code into existing IT governance processes.

Access control – AWS resources

Every request to AWS control plane resources (specifically, AWS APIs)—whether through the AWS Management Console, AWS Command Line Interface (AWS CLI), or SDK — is authenticated and authorized by IAM. To determine whether to approve or deny a specific request, IAM evaluates both the applicable policies associated with the requesting principal (human user or workload) and the respective request context. These policies come in the form of JSON documents and follow a specific schema that allows for automated evaluation.

IAM supports a range of different policy types that you can use to help protect your AWS resources and implement a least privilege approach. For an overview of the individual policy types and their purpose, see Policies and permissions in IAM. For some practical guidance on how and when to use them, see IAM policy types: How and when to use them. To learn more about the IAM policy evaluation process and the order in which IAM reviews individual policy types, see Policy evaluation logic.

Traditionally, IAM relied on role-based access control (RBAC) for authorization. With RBAC, principals are assigned predefined roles that grant only the minimum permissions needed to perform their duties (also known as a least privilege approach). RBAC can seem intuitive initially, but it can become cumbersome at scale. Every new resource that you add to AWS requires the IAM administrator to manually update each role’s permissions – a tedious process that can hamper agility in dynamic environments.

In contrast, attribute-based access control (ABAC) bases permissions on the attributes assigned to users and resources. IAM administrators define a policy that allows access when certain tags match. ABAC is especially advantageous for dynamic, fast-growing organizations that have outgrown the RBAC model. To learn more about how to implement ABAC in an AWS environment, see Define permissions to access AWS resources based on tags.

For a list of AWS services that IAM supports and whether each service supports ABAC, see AWS services that work with IAM.

Access control – Customer applications

Customer applications that run on AWS resources often require an authorization mechanism that can control access to the application itself and its individual functions in a fine-grained manner.

Many customer applications come with custom authorization mechanisms in the application code itself, making it challenging to implement policy changes. This approach can also hinder monitoring and auditing because the implementation of authorization logic often differs between applications, and there is no uniform standard.

To address this challenge, AWS developed Amazon Verified Permissions and the associated open-source policy language Cedar. Amazon Verified Permissions replaces the custom authorization logic in the application code with a simple IsAuthorized API call, so that you can control and monitor authorization logic centrally by using Cedar-based policies. To learn how to integrate Amazon Verified Permissions into your applications and define custom access control policies with Cedar, see How to use Amazon Verified Permissions for authorization.

Compliance

In addition to access control, you can also use policies to help monitor and enforce your organization’s individual governance rules for security, operations and compliance. AWS Config and AWS Security Hub play a central role in compliance because they enable the setup of multi-account environments that follow best practices (known as landing zones). AWS Config continuously tracks resource configurations and changes, while Security Hub aggregates and prioritizes security findings. With these services, you can create controls that enable automated audits and conformity checks. Alternatively, you can also choose from ready-to-use controls that cover individual compliance objectives such as encryption at rest, or entire frameworks, such as PCI-DSS and NIST 800-53.

AWS Control Tower builds on top of AWS Config and Security Hub to help simplify governance and compliance for multi-account environments. AWS Control Tower incorporates additional controls with the existing ones from AWS Config and Security Hub, presenting them together through a unified interface. These controls apply at different resource life cycle stages, as shown in Figure 1, and you define them through policies.

Figure 1: Resource life cycle

Figure 1: Resource life cycle

The controls can be categorized according to their behavior:

  • Proactive controls scan IaC templates before deployment to help identify noncompliance issues early.
  • Preventative controls restrict actions within an AWS environment to help prevent noncompliant actions. For example, these controls can help prevent deployment of large Amazon Elastic Compute Cloud (Amazon EC2) instances or restrict the available AWS Regions for some users.
  • Detective controls monitor deployed resources to help identify noncompliant resources that proactive and preventative controls might have missed. They also detect when deployed resources are changed or drift out of compliance over time.

Categorizing controls this way allows for a more comprehensive compliance framework that encompasses the entire resource life cycle. The stage at which each control applies determines how it may help enforce policies and governance rules.

With AWS Control Tower, you can enable hundreds of preconfigured security, compliance, and operational controls through the console with a single click, without needing to write code. You can also implement your own custom controls beyond what AWS Control Tower provides out of the box. The process for implementing custom controls varies depending on the type of control. In the following sections, I will explain how to set up custom controls for each type.

Proactive controls

Proactive controls are mechanisms that scan resources and their configuration to confirm that they adhere to compliance requirements before they are deployed. AWS provides a range of tools and services that you can use, both in isolation and in combination with each other, to implement proactive controls. The following diagram provides an overview of the available mechanisms and an example of their integration into a CI/CD pipeline for AWS Cloud Development Kit (CDK) projects.

Figure 2: CI/CD pipeline in AWS CDK projects

Figure 2: CI/CD pipeline in AWS CDK projects

As shown in Figure 2, you can use the following mechanisms as proactive controls:

  1. You can validate artifacts such as IaC templates locally on your machine by using the AWS CloudFormation Guard CLI, which facilitates a shift-left testing strategy. The advantage of this approach is the relatively early testing in the deployment cycle. This supports rapid iterative development and thus reduces waiting times.

    Alternatively, you can use the CfnGuardValidator plugin for AWS CDK, which integrates CloudFormation Guard rules into the AWS CDK CLI. This streamlines local development by applying policies and best practices directly within the CDK project.

  2. To centrally enforce validation checks, integrate the CfnGuardValidator plugin into a CDK CI/CD pipeline.
  3. You can also invoke the CloudFormation Guard CLI from within AWS CodeBuild buildspecs to embed CloudFormation Guard scans in a CI/CD pipeline.
  4. With CloudFormation hooks, you can impose policies on resources before CloudFormation deploys them.

AWS CloudFormation Guard uses a policy-as-code approach to evaluate IaC documents such as AWS CloudFormation templates and Terraform configuration files. The tool defines validation rules in the Guard language to check that these JSON or YAML documents align with best practices and organizational policies around provisioning cloud resources. By codifying rules and scanning infrastructure definitions programmatically, CloudFormation Guard automates policy enforcement and helps promote consistency and security across infrastructure deployments.

In the following example, you will use CloudFormation Guard to validate the name of an Amazon Simple Storage Service (Amazon S3) bucket in a CloudFormation template through a simple Guard rule:

To validate the S3 bucket

  1. Install CloudFormation Guard locally. For instructions, see Setting up AWS CloudFormation Guard.
  2. Create a YAML file named template.yaml with the following content and replace <DOC-EXAMPLE-BUCKET> with a bucket name of your choice (this file is a CloudFormation template, which creates an S3 bucket):
    Resources:
      S3Bucket:
        Type: 'AWS::S3::Bucket'
        Properties:
          BucketName: '<DOC-EXAMPLE-BUCKET>'

  3. Create a text file named rules.guard with the following content:
    rule checkBucketName {
        Resources.S3Bucket.Properties.BucketName == '<DOC-EXAMPLE-BUCKET>'
    }

  4. To validate your CloudFormation template against your Guard rules, run the following command in your local terminal:
    cfn-guard validate --rules rules.guard --data template.yaml

  5. If CloudFormation Guard successfully validates the template, the validate command produces an exit status of 0 ($? in bash). Otherwise, it returns a status report listing the rules that failed. You can test this yourself by changing the bucket name.

To accelerate the writing of Guard rules, use the CloudFormation Guard rulegen command, which takes a CloudFormation template file as an input and autogenerates Guard rules that match the properties of the template resources. To learn more about the structure of CloudFormation Guard rules and how to write them, see Writing AWS CloudFormation Guard rules.

The AWS Guard Rules Registry provides ready-to-use CloudFormation Guard rule files to accelerate your compliance journey, so that you don’t have to write them yourself.

Through the CDK plugin interface for policy validation, the CfnGuardValidator plugin integrates CloudFormation Guard rules into the AWS CDK and validates generated CloudFormation templates automatically during its synthesis step. For more details, see the plugin documentation and Accelerating development with AWS CDK plugin – CfnGuardValidator.

CloudFormation Guard alone can’t necessarily prevent the provisioning of noncompliant resources. This is because CloudFormation Guard can’t detect when templates or other documents change after validation. Therefore, I recommend that you combine CloudFormation Guard with a more authoritative mechanism.

One such mechanism is CloudFormation hooks, which you can use to validate AWS resources before you deploy them. You can configure hooks to cancel the deployment process with an alert if CloudFormation templates aren’t compliant, or just initiate an alert but complete the process. To learn more about CloudFormation hooks, see the following blog posts:

CloudFormation hooks provide a way to authoritatively enforce rules for resources deployed through CloudFormation. However, they don’t control resource creation that occurs outside of CloudFormation, such as through the console, CLI, SDK, or API. Terraform is one example that provisions resources directly through the AWS API rather than through CloudFormation templates. Because of this, I recommend that you implement additional detective controls by using AWS Config. AWS Config can continuously check resource configurations after deployment, regardless of the provisioning method. Using AWS Config rules complements the preventative capabilities of CloudFormation hooks.

Preventative controls

Preventative controls can help maintain compliance by applying guardrails that disallow policy-violating actions. AWS Control Tower integrates with AWS Organizations to implement preventative controls with SCPs. By using SCPs, you can restrict IAM permissions granted in a given organization or organizational unit (OU). One example of this is the selective activation of certain AWS Regions to meet data residency requirements.

SCPs are particularly valuable for managing IAM permissions across large environments with multiple AWS accounts. Organizations with many accounts might find it challenging to monitor and control IAM permissions. SCPs help address this challenge by applying centralized permission guardrails automatically to the accounts of an organization or organizational unit (OU). As new accounts are added, the SCPs are enforced without the need for extra configuration.

You can define SCPs through CloudFormation or CDK templates and deploy them through a CI/CD pipeline, similar to other AWS resources. Because misconfigured SCPs can negatively affect an organization’s operations, it’s vital that you test and simulate the effects of new policies in a sandbox environment before broader deployment. For an example of how to implement a pipeline for SCP testing, see the aws-service-control-policies-deployment GitHub repository.

To learn more about SCPs and how to implement them, see Service control policies (SCPs) and Best Practices for AWS Organizations Service Control Policies in a Multi-Account Environment.

Detective controls

Detective controls help detect noncompliance with existing resources. You can implement detective controls by using AWS Config rules, with both managed rules (provided by AWS) and custom rules available. You can implement custom rules either by using the domain-specific language Guard or Lambda functions. To learn more about the Guard option, see Evaluate custom configurations using AWS Config Custom Policy rules and the open source sample repository. For guidance on creating custom rules using Lambda functions, see AWS Config Rule Development Kit library: Build and operate rules at scale and Deploying Custom AWS Config Rules in an AWS Organization Environment.

To simplify audits for compliance frameworks such as PCI-DSS, HIPAA, and SOC2, AWS Config also offers conformance packs that bundle rules and remediation actions. To learn more about conformance packs, see Conformance Packs and Introducing AWS Config Conformance Packs.

When a resource’s configuration shifts to a noncompliant state that preventive controls didn’t avert, detective controls can help remedy the noncompliant state by implementing predefined actions, such as alerting an operator or reconfiguring the resource. You can implement these controls with AWS Config, which integrates with AWS Systems Manager Automation to help enable the remediation of noncompliant resources.

Security Hub can help centralize the detection of noncompliant resources across multiple AWS accounts. Using AWS Config and third-party tools for detection, Security Hub sends findings of noncompliance to Amazon EventBridge, which can then send notifications or launch automated remediations. You can also use the security controls and standards in Security Hub to monitor the configuration of your AWS infrastructure. This complements the conformance packs in AWS Config.

Conclusion

Many large and fast-growing organizations are faced with the challenge that manual IT governance processes are difficult to scale and can hinder growth. Policy-as-code services help to manage permissions and resource configurations at scale by automating key IT governance processes and, at the same time, increasing the quality and transparency of those processes. This helps to reconcile large environments with key governance objectives such as compliance.

In this post, you learned how to use policy as code to enhance IT governance. A first step is to activate AWS Control Tower, which provides preconfigured guardrails (SCPs) for each AWS account within an organization. These guardrails help enforce baseline compliance across infrastructure. You can then layer on additional controls to further strengthen governance in line with your needs. As a second step, you can select AWS Config conformance packs and Security Hub standards to complement the controls that AWS Control Tower offers. Finally, you can secure applications built on AWS by using Amazon Verified Permissions and Cedar for fine-grained authorization.

Resources

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Roland Odorfer

Roland Odorfer

Roland is a Solutions Architect at AWS, based in Berlin, Germany. He works with German industry and manufacturing customers, helping them architect secure and scalable solutions. Roland is interested in distributed systems and security. He enjoys helping customers use the cloud to solve complex challenges.

AWS Clean Rooms proof of concept scoping part 1: media measurement

Post Syndicated from Shaila Mathias original https://aws.amazon.com/blogs/big-data/aws-clean-rooms-proof-of-concept-scoping-part-1-media-measurement/

Companies are increasingly seeking ways to complement their data with external business partners’ data to build, maintain, and enrich their holistic view of their business at the consumer level. AWS Clean Rooms helps companies more easily and securely analyze and collaborate on their collective datasets—without sharing or copying each other’s underlying data. With AWS Clean Rooms, you can create a secure data clean room in minutes and collaborate with any other company on Amazon Web Services (AWS) to generate unique insights.

One way to quickly get started with AWS Clean Rooms is with a proof of concept (POC) between you and a priority partner. AWS Clean Rooms supports multiple industries and use cases, and this blog is the first of a series on types of proof of concepts that can be conducted with AWS Clean Rooms.

In this post, we outline planning a POC to measure media effectiveness in a paid advertising campaign. The collaborators are a media owner (“CTV.Co,” a connected TV provider) and brand advertiser (“Coffee.Co,” a quick service restaurant company), that are analyzing their collective data to understand the impact on sales as a result of an advertising campaign. We chose to start this series with media measurement because “Results & Measurement” was the top ranked use case for data collaboration by customers in a recent survey the AWS Clean Rooms team conducted.

Important to keep in mind

  • AWS Clean Rooms is generally available so any AWS customer can sign in to the AWS Management Console and start using the service today without additional paperwork.
  • With AWS Clean Rooms, you can perform two types of analyses: SQL queries and machine learning. For the purpose of this blog, we will be focusing only on SQL queries. You can learn more about both types of analyses and their cost structures on the AWS Clean Rooms Features and Pricing webpages. The AWS Clean Rooms team can help you estimate the cost of a POC and can be reached at [email protected].
  • While AWS Clean Rooms supports multiparty collaboration, we assume two members in the AWS Clean Rooms POC collaboration in this blog post.

Overview

Setting up a POC helps define an existing problem of a specific use case for using AWS Clean Rooms with your partners. After you’ve determined who you want to collaborate with, we recommend three steps to set up your POC:

  • Defining the business context and success criteria – Determine which partner, which use case should be tested, and what the success criteria are for the AWS Clean Rooms collaboration.
  • Aligning on the technical choices for this test – Make the technical decisions of who sets up the clean room, who is analyzing the data, which data sets are being used, join keys and what analysis is being run.
  • Outlining the workflow and timing – Create a workback plan, decide on synthetic data testing, and align on production data testing.

In this post, we walk through an example of how a quick service restaurant (QSR) coffee company (Coffee.Co) would set up a POC with a connected TV provider (CTV.Co) to determine the success of an advertising campaign.

Business context and success criteria for the POC

Define the use case to be tested

The first step in setting up the POC is defining the use case being tested with your partner in AWS Clean Rooms. For example, Coffee.Co wants to run a measurement analysis to determine the media exposure on CTV.Co that led to sign up for Coffee.Co’s loyalty program. AWS Clean Rooms allows for Coffee.Co and CTV.Co to collaborate and analyze their collective datasets without copying each other’s underlying data.

Success criteria

It’s important to determine metrics of success and acceptance criteria to move the POC to production upfront. For example, Coffee.Co’s goal is to achieve a sufficient match rate between their data set and CTV.Co’s data set to ensure the efficacy of the measurement analysis. Additionally, Coffee.Co wants ease-of-use for existing Coffee.Co team members to set up the collaboration and action on the insights driven from the collaboration to optimize future media spend to tactics on CTV.Co that will drive more loyalty members.

Technical choices for the POC

Determine the collaboration creator, AWS account IDs, query runner, payor and results receiver

Each AWS Clean Rooms collaboration is created by a single AWS account inviting other AWS accounts. The collaboration creator specifies which accounts are invited to the collaboration, who can run queries, who pays for the compute, who can receive the results, and the optional query logging and cryptographic computing settings. The creator is also able to remove members from a collaboration. In this POC, Coffee.Co initiates the collaboration by inviting CTV.Co. Additionally, Coffee.Co runs the queries and receives the results, but CTV.Co pays for the compute.

Query logging setting

If logging is enabled in the collaboration, AWS Clean Rooms allows each collaboration member to receive query logs. The collaborator running the queries, Coffee.Co, gets logs for all data tables while the other collaborator, CTV.Co, only sees the logs if their data tables are referenced in the query.

Decide the AWS region

The underlying Amazon Simple Storage Service (Amazon S3) and AWS Glue resources for the data tables used in the collaboration must be in the same AWS Region as the AWS Clean Rooms collaboration. For example, Coffee.Co and CTV.Co agree on the US East (Ohio) Region for their collaboration.

Join keys

To join data sets in an AWS Clean Rooms query, each side of the join must share a common key. Key join comparison with the equal to operator (=) must evaluate to True. AND or OR logical operators can be used in the inner join for matching on multiple join columns. Keys such as email address, phone number, or UID2 are often considered. Third party identifiers from LiveRamp, Experian, or Neustar can be used in the join through AWS Clean Rooms specific work flows with each partner.

If sensitive data is being used as join keys, it’s recommended to use an obfuscation technique to mitigate the risk of exposing sensitive data if the data is mishandled. Both parties must use a technique that produces the same obfuscated join key values such as hashing. Cryptographic Computing for Clean Rooms can be used for this propose.

In this POC, Coffee.Co and CTV.Co are joining on hashed email or hashed mobile. Both collaborators are using the SHA256 hash on their plaintext email and phone number when preparing their data sets for the collaboration.

Data schema

The exact data schema must be determined by collaborators to support the agreed upon analysis. In this POC, Coffee.Co is running a conversion analysis to measure media exposures on CTV.Co that led to sign-up for Coffee.Co’s loyalty program. Coffee.Co’s schema includes hashed email, hashed mobile, loyalty sign up date, loyalty membership type, and birthday of member. CTV.Co’s schema includes hashed email, hashed mobile, impressions, clicks, timestamp, ad placement, and ad placement type.

Analysis rule applied to each configured table associated to the collaboration

An AWS Clean Rooms configured table is a reference to an existing table in the AWS Glue Data Catalog that’s used in the collaboration. It contains an analysis rule that determines how the data can be queried in AWS Clean Rooms. Configured tables can be associated to one or more collaborations.

AWS Clean Rooms offers three types of analysis rules: aggregation, list, and custom.

  • Aggregation allows you to run queries that generate an aggregate statistic within the privacy guardrails set by each data owner. For example, how large the intersection of two datasets is.
  • List allows you to run queries that extract the row level list of the intersection of multiple data sets. For example, the overlapped records on two datasets.
  • Custom allows you to create custom queries and reusable templates using most industry standard SQL, as well as review and approve queries prior to your collaborator running them. For example, authoring an incremental lift query that’s the only query permitted to run on your data tables. You can also use AWS Clean Rooms Differential Privacy by selecting a custom analysis rule and then configuring your differential privacy parameters.

In this POC, CTV.Co uses the custom analysis rule and authors the conversion query. Coffee.Co adds this custom analysis rule to their data table, configuring the table for association to the collaboration. Coffee.Co is running the query, and can only run queries that CTV.Co authors on the collective datasets in this collaboration.

Planned query

Collaborators should define the query that will be run by the collaborator determined to run the queries. In this POC, Coffe.Co runs the custom analysis rule query CTV.Co authored to understand who signed up for their loyalty program after being exposed to an ad on CTV.Co. Coffee.Co can specify their desired time window parameter to analyze when the membership sign-up took place within a specific date range, because that parameter has been enabled in the custom analysis rule query.

Workflow and timeline

To determine the workflow and timeline for setting up the POC, the collaborators should set dates for the following activities.

  1. Coffee.Co and CTV.Co align on business context, success criteria, technical details, and prepare their data tables.
    • Example deadline: January 10.
  2. [Optional] Collaborators work to generate representative synthetic datasets for non-production testing prior to production data testing.
    • Example deadline: January 15
  3. [Optional] Each collaborator uses synthetic datasets to create an AWS Clean Rooms collaboration between two of their owned AWS non-production accounts and finalizes analysis rules and queries they want to run in production.
    • Example deadline: January 30
  4. [Optional] Coffee.Co and CTV.Co create an AWS Clean Rooms collaboration between non-production accounts and tests the analysis rules and queries with the synthetic datasets.
    • Example deadline: February 15
  5. Coffee.Co and CTV.Co create a production AWS Clean Rooms collaboration and run the POC queries on production data.
    • Example deadline: Feb 28
  6. Evaluate POC results against success criteria to determine when to move to production.
    • Example deadline March 15

Conclusion

After you’ve defined the business context and success criteria for the POC, aligned on the technical details, and outlined the workflow and timing, the goal of the POC is to run a successful collaboration using AWS Clean Rooms to validate moving to production. After you’ve validated that the collaboration is ready to move to production, AWS can help you identify and implement automation mechanisms to programmatically run AWS Clean Rooms for your production use cases. Watch this video to learn more about privacy-enhanced collaboration and contact an AWS Representative to learn more about AWS Clean Rooms.

About AWS Clean Rooms

AWS Clean Rooms helps companies and their partners more easily and securely analyze and collaborate on their collective datasets—without sharing or copying one another’s underlying data. With AWS Clean Rooms, customers can create a secure data clean room in minutes, and collaborate with any other company on AWS to generate unique insights about advertising campaigns, investment decisions, and research and development.

Additional resources


About the authors

Shaila Mathias  is a Business Development lead for AWS Clean Rooms at Amazon Web Services.

Allison Milone is a Product Marketer for the Advertising & Marketing Industry at Amazon Web Services.

Ryan Malecky is a Senior Solutions Architect at Amazon Web Services. He is focused on helping customers build gain insights from their data, especially with AWS Clean Rooms.

Prepare and load Amazon S3 data into Teradata using AWS Glue through its native connector for Teradata Vantage

Post Syndicated from Vinod Jayendra original https://aws.amazon.com/blogs/big-data/prepare-and-load-amazon-s3-data-into-teradata-using-aws-glue-through-its-native-connector-for-teradata-vantage/

In this post, we explore how to use the AWS Glue native connector for Teradata Vantage to streamline data integrations and unlock the full potential of your data.

Businesses often rely on Amazon Simple Storage Service (Amazon S3) for storing large amounts of data from various data sources in a cost-effective and secure manner. For those using Teradata for data analysis, integrations through the AWS Glue native connector for Teradata Vantage unlock new possibilities. AWS Glue enhances the flexibility and efficiency of data management, allowing companies to seamlessly integrate their data, regardless of its location, with Teradata’s analytical capabilities. This new connector eliminates technical hurdles related to configuration, security, and management, enabling companies to effortlessly export or import their datasets into Teradata Vantage. As a result, businesses can focus more on extracting meaningful insights from their data, rather than dealing with the intricacies of data integration.

AWS Glue is a serverless data integration service that makes it straightforward for analytics users to discover, prepare, move, and integrate data from multiple sources for analytics, machine learning (ML), and application development. With AWS Glue, you can discover and connect to more than 100 diverse data sources and manage your data in a centralized data catalog. You can visually create, run, and monitor extract, transform, and load (ETL) pipelines to load data into your data lakes.

Teradata Corporation is a leading connected multi-cloud data platform for enterprise analytics, focused on helping companies use all their data across an enterprise, at scale. As an AWS Data & Analytics Competency partner, Teradata offers a complete cloud analytics and data platform, including for Machine Learning.

Introducing the AWS Glue native connector for Teradata Vantage

AWS Glue provides support for Teradata, accessible through both AWS Glue Studio and AWS Glue ETL scripts. With AWS Glue Studio, you benefit from a visual interface that simplifies the process of connecting to Teradata and authoring, running, and monitoring AWS Glue ETL jobs. For data developers, this support extends to AWS Glue ETL scripts, where you can use Python or Scala to create and manage more specific data integration and transformation tasks.

The AWS Glue native connector for Teradata Vantage allows you to efficiently read and write data from Teradata without the need to install or manage any connector libraries. You can add Teradata as both the source and target within AWS Glue Studio’s no-code, drag-and-drop visual interface or use the connector directly in an AWS Glue ETL script job.

Solution overview

In this example, you use AWS Glue Studio to enrich and upload data stored on Amazon S3 to Teradata Vantage. You start by joining the Event and Venue files from the TICKIT dataset. Next, you filter the results to a single geographic region. Finally, you upload the refined data to Teradata Vantage.

The TICKIT dataset tracks sales activity for the fictional TICKIT website, where users buy and sell tickets online for sporting events, shows, and concerts. In this dataset, analysts can identify ticket movement over time, success rates for sellers, and best-selling events, venues, and seasons.

For this example, you use AWS Glue Studio to develop a visual ETL pipeline. This pipeline will read data from Amazon S3, perform transformations, and then load the transformed data into Teradata. The following diagram illustrates this architecture.

Solution Overview

By the end of this post, your visual ETL job will resemble the following screenshot.

Visual ETL Job Flow

Prerequisites

For this example, you should have access to an existing Teradata database endpoint with network reachability from AWS and permissions to create tables and load and query data.

AWS Glue needs network access to Teradata to read or write data. How this is configured depends on where your Teradata is deployed and the specific network configuration. For Teradata deployed on AWS, you might need to configure VPC peering or AWS PrivateLink, security groups, and network access control lists (NACLs) to allow AWS Glue to communicate with Teradata overt TCP. If Teradata is outside AWS, networking services such as AWS Site-to-Site VPN or AWS Direct Connect may be required. Public internet access is not recommended due to security risks. If you choose public access, it’s safer to run the AWS Glue job in a VPC behind a NAT gateway. This approach enables you to allow list only one IP address for incoming traffic on your network firewall. For more information, refer to Infrastructure security in AWS Glue.

Set up Amazon S3

Every object in Amazon S3 is stored in a bucket. Before you can store data in Amazon S3, you must create an S3 bucket to store the results. Complete the following steps:

  1. On the Amazon S3 console, choose Buckets in the navigation pane.
  2. Choose Create bucket.
  3. For Name, enter a globally unique name for your bucket; for example, tickit8530923.
  4. Choose Create bucket.
  5. Download the TICKIT dataset and unzip it.
  6. Create the folder tickit in your S3 bucket and upload the allevents_pipe.txt and venue_pipe.txt files.

Configure Teradata connections

To connect to Teradata from AWS Glue, see Configuring Teradata Connection.

You must create and store your Teradata credentials in an AWS Secrets Manager secret and then associate that secret with a Teradata AWS Glue connection. We discuss these two steps in more detail later in this post.

Create an IAM role for the AWS Glue ETL job

When you create the AWS Glue ETL job, you specify an AWS Identity and Access Management (IAM) role for the job to use. The role must grant access to all resources used by the job, including Amazon S3 (for any sources, targets, scripts, driver files, and temporary directories) and Secrets Manager. For instructions, see Configure an IAM role for your ETL job.

Create table in Teradata

Using your preferred database tool, log in to Teradata. Run the following code to create the table in Teradata where you will load your data:

CREATE MULTISET TABLE test.tickit, FALLBACK
   (venueid varchar(25),
    venuename varchar(100),
    venuecity varchar(100),
    venuestate varchar(25),
    venueseats varchar(25),
    eventid varchar(25),
    catid varchar(25),
    dateid varchar(25),
    eventname varchar(100),
    starttime varchar(100))
    NO PRIMARY INDEX
;

Store Teradata login credentials

An AWS Glue connection is a Data Catalog object that stores login credentials, URI strings, and more. The Teradata connector requires Secrets Manager for storing the Teradata user name and password that you use to connect to Teradata.

To store the Teradata user name and password in Secrets Manager, complete the following steps:

  1. On the Secrets Manager console, choose Secrets in the navigation pane.
  2. Choose Store a new secret.
  3. Select Other type of secret.
  4. Enter the key/value USER and teradata_user, then choose Add row.
  5. Enter the key/value PASSWORD and teradata_user_password, then choose Next.

Teradata Secrets Manager Configuration

  1. For Secret name, enter a descriptive name, then choose Next.
  2. Choose Next to move to the review step, then choose Store.

Create the Teradata connection in AWS Glue

Now you’re ready to create an AWS Glue connection to Teradata. Complete the following steps:

  1. On the AWS Glue console, choose Connections under Data Catalog in the navigation pane.
  2. Choose Create connection.
  3. For Name, enter a name (for example, teradata_connection).
  4. For Connection type¸ choose Teradata.
  5. For Teradata URL, enter jdbc:teradata://url_of_teradata/database=name_of_your_database.
  6. For AWS Secret, choose the secret with your Teradata credentials that you created earlier.

Teradata Connection access

Create an AWS Glue visual ETL job to transform and load data to Teradata

Complete the following steps to create your AWS Glue ETL job:

  1. On the AWS Glue console, under ETL Jobs in the navigation pane, choose Visual ETL.
  2. Choose Visual ETL.
  3. Choose the pencil icon to enter a name for your job.

We add venue_pipe.txt as our first dataset.

  1. Choose Add nodes and choose Amazon S3 on the Sources tab.

Amazon S3 source node

  1. Enter the following data source properties:
    1. For Name, enter Venue.
    2. For S3 source type, select S3 location.
    3. For S3 URL, enter the S3 path to venue_pipe.txt.
    4. For Data format, choose CSV.
    5. For Delimiter, choose Pipe.
    6. Deselect First line of source file contains column headers.

S3 data source properties

Now we add allevents_pipe.txt as our second dataset.

  1. Choose Add nodes and choose Amazon S3 on the Sources tab.
  2. Enter the following data source properties:
    1. For Name, enter Event.
    2. For S3 source type, select S3 location.
    3. For S3 URL, enter the S3 path to allevents_pipe.txt.
    4. For Data format, choose CSV.
    5. For Delimiter, choose Pipe.
    6. Deselect First line of source file contains column headers.

Next, we rename the columns of the Venue dataset.

  1. Choose Add nodes and choose Change Schema on the Transforms tab.
  2. Enter the following transform properties:
    1. For Name, enter Rename Venue data.
    2. For Node parents, choose Venue.
    3. In the Change Schema section, map the source keys to the target keys:
      1. col0: venueid
      2. col1: venuename
      3. col2: venuecity
      4. col3: venuestate
      5. col4: venueseats

Rename Venue data ETL Transform

Now we filter the Venue dataset to a specific geographic region.

  1. Choose Add nodes and choose Filter on the Transforms tab.
  2. Enter the following transform properties:
    1. For Name, enter Location Filter.
    2. For Node parents, choose Venue.
    3. For Filter condition, choose venuestate for Key, choose matches for Operation, and enter DC for Value.

Location Filter Settings

Now we rename the columns in the Event dataset.

  1. Choose Add nodes and choose Change Schema on the Transforms tab.
  2. Enter the following transform properties:
    1. For Name, enter Rename Event data.
    2. For Node parents, choose Event.
    3. In the Change Schema section, map the source keys to the target keys:
      1. col0: eventid
      2. col1: e_venueid
      3. col2: catid
      4. col3: dateid
      5. col4: eventname
      6. col5: starttime

Next, we join the Venue and Event datasets.

  1. Choose Add nodes and choose Join on the Transforms tab.
  2. Enter the following transform properties:
    1. For Name, enter Join.
    2. For Node parents, choose Location Filter and Rename Event data.
    3. For Join type¸ choose Inner join.
    4. For Join conditions, choose venueid for Location Filter and e_venueid for Rename Event data.

Join Properties

Now we drop the duplicate column.

  1. Choose Add nodes and choose Change Schema on the Transforms tab.
  2. Enter the following transform properties:
    1. For Name, enter Drop column.
    2. For Node parents, choose Join.
    3. In the Change Schema section, select Drop for e_venueid .

Drop column properties

Next, we load the data into the Teradata table.

  1. Choose Add nodes and choose Teradata on the Targets tab.
  2. Enter the following data sink properties:
    1. For Name, enter Teradata.
    2. For Node parents, choose Drop column.
    3. For Teradata connection, choose teradata_connection.
    4. For Table name, enter schema.tablename of the table you created in Teradata.

Data sink properties Teradata

Lastly, we run the job and load the data into Teradata.

  1. Choose Save, then choose Run.

A banner will display that the job has started.

  1. Choose Runs, which displays the status of the job.

The run status will change to Succeeded when the job is complete.

Run Status

  1. Connect to your Teradata and then query the table the data was loaded to it.

The filtered and joined data from the two datasets will be in the table.

Filtered and joined data result

Clean up

To avoid incurring additional charges caused by resources created as part of this post, make sure you delete the items you created in the AWS account for this post:

  • The Secrets Manager key created for the Teradata credentials
  • The AWS Glue native connector for Teradata Vantage
  • The data loaded in the S3 bucket
  • The AWS Glue Visual ETL job

Conclusion

In this post, you created a connection to Teradata using AWS Glue and then created an AWS Glue job to transform and load data into Teradata. The AWS Glue native connector for Teradata Vantage empowers your data analytics journey by providing a seamless and efficient pathway for integrating your data with Teradata. This new capability in AWS Glue not only simplifies your data integration workflows but also opens up new avenues for advanced analytics, business intelligence, and machine learning innovations.

With the AWS Teradata Connector, you have the best tool at your disposal for simplifying data integration tasks. Whether you’re looking to load Amazon S3 data into Teradata for analytics, reporting, or business insights, this new connector streamlines the process, making it more accessible and cost-effective.

To get started with AWS Glue, refer to Getting Started with AWS Glue.


About the Authors

Kamen Sharlandjiev is a Sr. Big Data and ETL Solutions Architect and AWS Glue expert. He’s on a mission to make life easier for customers who are facing complex data integration challenges. His secret weapon? Fully managed, low-code AWS services that can get the job done with minimal effort and no coding. Follow Kamen on LinkedIn to keep up to date with the latest AWS Glue news!

Sean Bjurstrom is a Technical Account Manager in ISV accounts at Amazon Web Services, where he specializes in analytics technologies and draws on his background in consulting to support customers on their analytics and cloud journeys. Sean is passionate about helping businesses harness the power of data to drive innovation and growth. Outside of work, he enjoys running and has participated in several marathons.

Vinod Jayendra is an Enterprise Support Lead in ISV accounts at Amazon Web Services, where he helps customers solve their architectural, operational, and cost-optimization challenges. With a particular focus on serverless technologies, he draws from his extensive background in application development to help customers build top-tier solutions. Beyond work, he finds joy in quality family time, embarking on biking adventures, and coaching youth sports teams.

Doug Mbaya is a Senior Partner Solution architect with a focus in analytics and machine learning. Doug works closely with AWS partners and helps them integrate their solutions with AWS analytics and machine learning solutions in the cloud.

Optimize AWS administration with IAM paths

Post Syndicated from David Rowe original https://aws.amazon.com/blogs/security/optimize-aws-administration-with-iam-paths/

As organizations expand their Amazon Web Services (AWS) environment and migrate workloads to the cloud, they find themselves dealing with many AWS Identity and Access Management (IAM) roles and policies. These roles and policies multiply because IAM fills a crucial role in securing and controlling access to AWS resources. Imagine you have a team creating an application. You create an IAM role to grant them access to the necessary AWS resources, such as Amazon Simple Storage Service (Amazon S3) buckets, Amazon Key Management Service (Amazon KMS) keys, and Amazon Elastic File Service (Amazon EFS) shares. With additional workloads and new data access patterns, the number of IAM roles and policies naturally increases. With the growing complexity of resources and data access patterns, it becomes crucial to streamline access and simplify the management of IAM policies and roles

In this blog post, we illustrate how you can use IAM paths to organize IAM policies and roles and provide examples you can use as a foundation for your own use cases.

How to use paths with your IAM roles and policies

When you create a role or policy, you create it with a default path. In IAM, the default path for resources is “/”. Instead of using a default path, you can create and use paths and nested paths as a structure to manage IAM resources. The following example shows an IAM role named S3Access in the path developer:

arn:aws:iam::111122223333:role/developer/S3Access

Service-linked roles are created in a reserved path /aws-service-role/. The following is an example of a service-linked role path.

arn:aws:iam::*:role/aws-service-role/SERVICE-NAME.amazonaws.com/SERVICE-LINKED-ROLE-NAME

The following example is of an IAM policy named S3ReadOnlyAccess in the path security:

arn:aws:iam::111122223333:policy/security/S3ReadOnlyAccess

Why use IAM paths with roles and policies?

By using IAM paths with roles and policies, you can create groupings and design a logical separation to simplify management. You can use these groupings to grant access to teams, delegate permissions, and control what roles can be passed to AWS services. In the following sections, we illustrate how to use IAM paths to create groupings of roles and policies by referencing a fictional company and its expansion of AWS resources.

First, to create roles and policies with a path, you use the IAM API or AWS Command Line Interface (AWS CLI) to run aws cli create-role.

The following is an example of an AWS CLI command that creates a role in an IAM path.

aws iam create-role --role-name <ROLE-NAME> --assume-role-policy-document file://assume-role-doc.json --path <PATH>

Replace <ROLE-NAME> and <PATH> in the command with your role name and role path respectively. Use a trust policy for the trust document that matches your use case. An example trust policy that allows Amazon Elastic Compute Cloud (Amazon EC2) instances to assume this role on your behalf is below:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": [
                "sts:AssumeRole"
            ],
            "Principal": {
                "Service": [
                    "ec2.amazonaws.com"
                ]
            }
        }
    ]
}

The following is an example of an AWS CLI command that creates a policy in an IAM path.

aws iam create-policy --policy-name <POLICY-NAME> --path <PATH> --policy-document file://policy.json

IAM paths sample implementation

Let’s assume you’re a cloud platform architect at AnyCompany, a startup that’s planning to expand its AWS environment. By the end of the year, AnyCompany is going to expand from one team of developers to multiple teams, all of which require access to AWS. You want to design a scalable way to manage IAM roles and policies to simplify the administrative process to give permissions to each team’s roles. To do that, you create groupings of roles and policies based on teams.

Organize IAM roles with paths

AnyCompany decided to create the following roles based on teams.

Team name Role name IAM path Has access to
Security universal-security-readonly /security/ All resources
Team A database administrators DBA-role-A /teamA/ TeamA’s databases
Team B database administrators DBA-role-B /teamB/ TeamB’s databases

The following are example Amazon Resource Names (ARNs) for the roles listed above. In this example, you define IAM paths to create a grouping based on team names.

  1. arn:aws:iam::444455556666:role/security/universal-security-readonly-role
  2. arn:aws:iam::444455556666:role/teamA/DBA-role-A
  3. arn:aws:iam::444455556666:role/teamB/DBA-role-B

Note: Role names must be unique within your AWS account regardless of their IAM paths. You cannot have two roles named DBA-role, even if they’re in separate paths.

Organize IAM policies with paths

After you’ve created roles in IAM paths, you will create policies to provide permissions to these roles. The same path structure that was defined in the IAM roles is used for the IAM policies. The following is an example of how to create a policy with an IAM path. After you create the policy, you can attach the policy to a role using the attach-role-policy command.

aws iam create-policy --policy-name <POLICY-NAME> --policy-document file://policy-doc.json --path <PATH>
  1. arn:aws:iam::444455556666:policy/security/universal-security-readonly-policy
  2. arn:aws:iam::444455556666:policy/teamA/DBA-policy-A
  3. arn:aws:iam::444455556666:policy/teamB/DBA-policy-B

Grant access to groupings of IAM roles with resource-based policies

Now that you’ve created roles and policies in paths, you can more readily define which groups of principals can access a resource. In this deny statement example, you allow only the roles in the IAM path /teamA/ to act on your bucket, and you deny access to all other IAM principals. Rather than use individual roles to deny access to the bucket, which would require you to list every role, you can deny access to an entire group of principals by path. If you create a new role in your AWS account in the specified path, you don’t need to modify the policy to include them. The path-based deny statement will apply automatically.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Action": "s3:*",
      "Effect": "Deny",
      "Resource": [
		"arn:aws:s3:::EXAMPLE-BUCKET",
		"arn:aws:s3:::EXAMPLE-BUCKET/*"
		],
      "Principal": "*",
"Condition": {
        "ArnNotLike": {
          "aws:PrincipalArn": "arn:aws:iam::*:role/teamA/*"
        }
      }
}
  ]
}

Delegate access with IAM paths

IAM paths can also enable teams to more safely create IAM roles and policies and allow teams to only use the roles and policies contained by the paths. Paths can help prevent teams from privilege escalation by denying the use of roles that don’t belong to their team.

Continuing the example above, AnyCompany established a process that allows each team to create their own IAM roles and policies, providing they’re in a specified IAM path. For example, AnyCompany allows team A to create IAM roles and policies for team A in the path /teamA/:

  1. arn:aws:iam::444455556666:role/teamA/<role-name>
  2. arn:aws:iam::444455556666:policy/teamA/<policy-name>

Using IAM paths, AnyCompany can allow team A to more safely create and manage their own IAM roles and policies and safely pass those roles to AWS services using the iam:PassRole permission.

At AnyCompany, four IAM policies using IAM paths allow teams to more safely create and manage their own IAM roles and policies. Following recommended best practices, AnyCompany uses infrastructure as code (IaC) for all IAM role and policy creation. The four path-based policies that follow will be attached to each team’s CI/CD pipeline role, which has permissions to create roles. The following example focuses on team A, and how these policies enable them to self-manage their IAM credentials.

  1. Create a role in the path and modify inline policies on the role: This policy allows three actions: iam:CreateRole, iam:PutRolePolicy, and iam:DeleteRolePolicy. When this policy is attached to a principal, that principal is allowed to create roles in the IAM path /teamA/ and add and delete inline policies on roles in that IAM path.
    {
      "Version": "2012-10-17",
      "Statement": [
    {
            "Effect": "Allow",
            "Action": [
                "iam:CreateRole",
                "iam:PutRolePolicy",
                "iam:DeleteRolePolicy"
            ],
            "Resource": "arn:aws:iam::444455556666:role/teamA/*"
        }
    ]
    }

  2. Add and remove managed policies: The second policy example allows two actions: iam:AttachRolePolicy and iam:DetachRolePolicy. This policy allows a principal to attach and detach managed policies in the /teamA/ path to roles that are created in the /teamA/ path.
    {
      "Version": "2012-10-17",
      "Statement": [
    
    {
            "Effect": "Allow",
            "Action": [
                "iam:AttachRolePolicy",
                "iam:DetachRolePolicy"
            ],
            "Resource": "arn:aws:iam::444455556666:role/teamA/*",
            "Condition": {
                "ArnLike": {
                    "iam:PolicyARN": "arn:aws:iam::444455556666:policy/teamA/*"
                }          
            }
        }
    ]}

  3. Delete roles, tag and untag roles, read roles: The third policy allows a principal to delete roles, tag and untag roles, and retrieve information about roles that are created in the /teamA/ path.
    {
      "Version": "2012-10-17",
      "Statement": [
    
    
    {
            "Effect": "Allow",
            "Action": [
                "iam:DeleteRole",
                "iam:TagRole",
                "iam:UntagRole",
                "iam:GetRole",
                "iam:GetRolePolicy"
            ],
            "Resource": "arn:aws:iam::444455556666:role/teamA/*"
        }]}

  4. Policy management in IAM path: The final policy example allows access to create, modify, get, and delete policies that are created in the /teamA/ path. This includes creating, deleting, and tagging policies.
    {
      "Version": "2012-10-17",
      "Statement": [
    
    {
            "Effect": "Allow",
            "Action": [
                "iam:CreatePolicy",
                "iam:DeletePolicy",
                "iam:CreatePolicyVersion",            
                "iam:DeletePolicyVersion",
                "iam:GetPolicy",
                "iam:TagPolicy",
                "iam:UntagPolicy",
                "iam:SetDefaultPolicyVersion",
                "iam:ListPolicyVersions"
             ],
            "Resource": "arn:aws:iam::444455556666:policy/teamA/*"
        }]}

Safely pass roles with IAM paths and iam:PassRole

To pass a role to an AWS service, a principal must have the iam:PassRole permission. IAM paths are the recommended option to restrict which roles a principal can pass when granted the iam:PassRole permission. IAM paths help verify principals can only pass specific roles or groupings of roles to an AWS service.

At AnyCompany, the security team wants to allow team A to add IAM roles to an instance profile and attach it to Amazon EC2 instances, but only if the roles are in the /teamA/ path. The IAM action that allows team A to provide the role to the instance is iam:PassRole. The security team doesn’t want team A to be able to pass other roles in the account, such as an administrator role.

The policy that follows allows passing of a role that was created in the /teamA/ path and does not allow the passing of other roles such as an administrator role.

{
    "Version": "2012-10-17",
    "Statement": [{
        "Effect": "Allow",
        "Action": "iam:PassRole",
        "Resource": "arn:aws:iam::444455556666:role/teamA/*"
    }]
}

How to create preventative guardrails for sensitive IAM paths

You can use service control policies (SCP) to restrict access to sensitive roles and policies within specific IAM paths. You can use an SCP to prevent the modification of sensitive roles and policies that are created in a defined path.

You will see the IAM path under the resource and condition portion of the statement. Only the role named IAMAdministrator created in the /security/ path can create or modify roles in the security path. This SCP allows you to delegate IAM role and policy management to developers with confidence that they won’t be able to create, modify, or delete any roles or policies in the security path.

{
    "Version": "2012-10-17",
    "Statement": [
        {
	    "Sid": "RestrictIAMWithPathManagement",
            "Effect": "Deny",
            "Action": [
                "iam:AttachRolePolicy",
                "iam:CreateRole",
                "iam:DeleteRole",
                "iam:DeleteRolePermissionsBoundary",
                "iam:DeleteRolePolicy",
                "iam:DetachRolePolicy",
                "iam:PutRolePermissionsBoundary",
                "iam:PutRolePolicy",
                "iam:UpdateRole",
                "iam:UpdateAssumeRolePolicy",
                "iam:UpdateRoleDescription",
                "sts:AssumeRole",
                "iam:TagRole",
                "iam:UntagRole"
            ],
            "Resource": [
                "arn:aws:iam::*:role/security/* "
            ],
            "Condition": {
                "ArnNotLike": {
                    "aws:PrincipalARN": "arn:aws:iam::444455556666:role/security/IAMAdministrator"
                }
            }
        }
    ]
}

This next example shows you how you can safely exempt IAM roles created in the security path from specific controls in your organization. The policy denies all roles except the roles created in the /security/ IAM path to close member accounts.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "PreventCloseAccount",
      "Effect": "Deny",
      "Action": "organizations:CloseAccount",
      "Resource": "*",
      "Condition": {
        "ArnNotLikeIfExists": {
          "aws:PrincipalArn": [
            "arn:aws:iam::*:role/security/*"
          ]
        }
      }
    }
  ]
}

Additional considerations when using IAM paths

You should be aware of some additional considerations when you start using IAM paths.

  1. Paths are immutable for IAM roles and policies. To change a path, you must delete the IAM resource and recreate the IAM resource in the alternative path. Deleting roles or instance profiles has step-by-step instructions to delete an IAM resource.
  2. You can only create IAM paths using AWS API or command line tools. You cannot create IAM paths with the AWS console.
  3. IAM paths aren’t added to the uniqueness of the role name. Role names must be unique within your account without the path taken into consideration.
  4. AWS reserves several paths including /aws-service-role/ and you cannot create roles in this path.

Conclusion

IAM paths provide a powerful mechanism for effectively grouping IAM resources. Path-based groupings can streamline access management across AWS services. In this post, you learned how to use paths with IAM principals to create structured access with IAM roles, how to delegate and segregate access within an account, and safely pass roles using iam:PassRole. These techniques can empower you to fine-tune your AWS access management and help improve security while streamlining operational workflows.

You can use the following references to help extend your knowledge of IAM paths. This post references the processes outlined in the user guides and blog post, and sources the IAM policies from the GitHub repositories.

  1. AWS Organizations User Guide, SCP General Examples
  2. AWS-Samples Service-control-policy-examples GitHub Repository
  3. AWS Security Blog: IAM Policy types: How and when to use them
  4. AWS-Samples how-and-when-to-use-aws-iam-policy-blog-samples GitHub Repository

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

David Rowe

David Rowe

As a Senior Solutions Architect, David unites diverse global teams to drive cloud transformation through strategies and intuitive identity solutions. He creates consensus, guiding teams to adopt emerging technologies. He thrives on bringing together cross-functional perspectives to transform vision into reality in dynamic industries.

Security at multiple layers for web-administered apps

Post Syndicated from Guy Morton original https://aws.amazon.com/blogs/security/security-at-multiple-layers-for-web-administered-apps/

In this post, I will show you how to apply security at multiple layers of a web application hosted on AWS.

Apply security at all layers is a design principle of the Security pillar of the AWS Well-Architected Framework. It encourages you to apply security at the network edge, virtual private cloud (VPC), load balancer, compute instance (or service), operating system, application, and code.

Many popular web apps are designed with a single layer of security: the login page. Behind that login page is an in-built administration interface that is directly exposed to the internet. Admin interfaces for these apps typically have simple login mechanisms and often lack multi-factor authentication (MFA) support, which can make them an attractive target for threat actors.

The in-built admin interface can also be problematic if you want to horizontally scale across multiple servers. The admin interface is available on every server that runs the app, so it creates a large attack surface. Because the admin interface updates the software on its own server, you must synchronize updates across a fleet of instances.

Multi-layered security is about identifying (or creating) isolation boundaries around the parts of your architecture and minimizing what is permitted to cross each boundary. Adding more layers to your architecture gives you the opportunity to introduce additional controls at each layer, creating more boundaries where security controls can be enforced.

In the example app scenario in this post, you have the opportunity to add many additional layers of security.

Example of multi-layered security

This post demonstrates how you can use the Run Web-Administered Apps on AWS sample project to help address these challenges, by implementing a horizontally-scalable architecture with multi-layered security. The project builds and configures many different AWS services, each designed to help provide security at different layers.

By running this solution, you can produce a segmented architecture that separates the two functions of these apps into an unprivileged public-facing view and an admin view. This design limits access to the web app’s admin functions while creating a fleet of unprivileged instances to serve the app at scale.

Figure 1 summarizes how the different services in this solution work to help provide security at the following layers:

  1. At the network edge
  2. Within the VPC
  3. At the load balancer
  4. On the compute instances
  5. Within the operating system
Figure 1: Logical flow diagram to apply security at multiple layers

Figure 1: Logical flow diagram to apply security at multiple layers

Deep dive on a multi-layered architecture

The following diagram shows the solution architecture deployed by Run Web-Administered Apps on AWS. The figure shows how the services deployed in this solution are deployed in different AWS Regions, and how requests flow from the application user through the different service layers.

Figure 2: Multi-layered architecture

Figure 2: Multi-layered architecture

This post will dive deeper into each of the architecture’s layers to see how security is added at each layer. But before we talk about the technology, let’s consider how infrastructure is built and managed — by people.

Perimeter 0 – Security at the people layer

Security starts with the people in your team and your organization’s operational practices. How your “people layer” builds and manages your infrastructure contributes significantly to your security posture.

A design principle of the Security pillar of the Well-Architected Framework is to automate security best practices. This helps in two ways: it reduces the effort required by people over time, and it helps prevent resources from being in inconsistent or misconfigured states. When people use manual processes to complete tasks, misconfigurations and missed steps are common.

The simplest way to automate security while reducing human effort is to adopt services that AWS manages for you, such as Amazon Relational Database Service (Amazon RDS). With Amazon RDS, AWS is responsible for the operating system and database software patching, and provides tools to make it simple for you to back up and restore your data.

You can automate and integrate key security functions by using managed AWS security services, such as Amazon GuardDuty, AWS Config, Amazon Inspector, and AWS Security Hub. These services provide network monitoring, configuration management, and detection of software vulnerabilities and unintended network exposure. As your cloud environments grow in scale and complexity, automated security monitoring is critical.

Infrastructure as code (IaC) is a best practice that you can follow to automate the creation of infrastructure. By using IaC to define, configure, and deploy the AWS resources that you use, you reduce the likelihood of human error when building AWS infrastructure.

Adopting IaC can help you improve your security posture because it applies the rigor of application code development to infrastructure provisioning. Storing your infrastructure definition in a source control system (such as AWS CodeCommit) creates an auditable artifact. With version control, you can track changes made to it over time as your architecture evolves.

You can add automated testing to your IaC project to help ensure that your infrastructure is aligned with your organization’s security policies. If you ever need to recover from a disaster, you can redeploy the entire architecture from your IaC project.

Another people-layer discipline is to apply the principle of least privilege. AWS Identity and Access Management (IAM) is a flexible and fine-grained permissions system that you can use to grant the smallest set of actions that your solution needs. You can use IAM to control access for both humans and machines, and we use it in this project to grant the compute instances the least privileges required.

You can also adopt other IAM best practices such as using temporary credentials instead of long-lived ones (such as access keys), and regularly reviewing and removing unused users, roles, permissions, policies, and credentials.

Perimeter 1 – network protections

The internet is public and therefore untrusted, so you must proactively address the risks from threat actors and network-level attacks.

To reduce the risk of distributed denial of service (DDoS) attacks, this solution uses AWS Shield for managed protection at the network edge. AWS Shield Standard is automatically enabled for all AWS customers at no additional cost and is designed to provide protection from common network and transport layer DDoS attacks. For higher levels of protection against attacks that target your applications, subscribe to AWS Shield Advanced.

Amazon Route 53 resolves the hostnames that the solution uses and maps the hostnames as aliases to an Amazon CloudFront distribution. Route 53 is a robust and highly available globally distributed DNS service that inspects requests to protect against DNS-specific attack types, such as DNS amplification attacks.

Perimeter 2 – request processing

CloudFront also operates at the AWS network edge and caches, transforms, and forwards inbound requests to the relevant origin services across the low-latency AWS global network. The risk of DDoS attempts overwhelming your application servers is further reduced by caching web requests in CloudFront.

The solution configures CloudFront to add a shared secret to the origin request within a custom header. A CloudFront function copies the originating user’s IP to another custom header. These headers get checked when the request arrives at the load balancer.

AWS WAF, a web application firewall, blocks known bad traffic, including cross-site scripting (XSS) and SQL injection events that come into CloudFront. This project uses AWS Managed Rules, but you can add your own rules, as well. To restrict frontend access to permitted IP CIDR blocks, this project configures an IP restriction rule on the web application firewall.

Perimeter 3 – the VPC

After CloudFront and AWS WAF check the request, CloudFront forwards it to the compute services inside an Amazon Virtual Private Cloud (Amazon VPC). VPCs are logically isolated networks within your AWS account that you can use to control the network traffic that is allowed in and out. This project configures its VPC to use a private IPv4 CIDR block that cannot be directly routed to or from the internet, creating a network perimeter around your resources on AWS.

The Amazon Elastic Compute Cloud (Amazon EC2) instances are hosted in private subnets within the VPC that have no inbound route from the internet. Using a NAT gateway, instances can make necessary outbound requests. This design hosts the database instances in isolated subnets that don’t have inbound or outbound internet access. Amazon RDS is a managed service, so AWS manages patching of the server and database software.

The solution accesses AWS Secrets Manager by using an interface VPC endpoint. VPC endpoints use AWS PrivateLink to connect your VPC to AWS services as if they were in your VPC. In this way, resources in the VPC can communicate with Secrets Manager without traversing the internet.

The project configures VPC Flow Logs as part of the VPC setup. VPC flow logs capture information about the IP traffic going to and from network interfaces in your VPC. GuardDuty analyzes these logs and uses threat intelligence data to identify unexpected, potentially unauthorized, and malicious activity within your AWS environment.

Although using VPCs and subnets to segment parts of your application is a common strategy, there are other ways that you can achieve partitioning for application components:

  • You can use separate VPCs to restrict access to a database, and use VPC peering to route traffic between them.
  • You can use a multi-account strategy so that different security and compliance controls are applied in different accounts to create strong logical boundaries between parts of a system. You can route network requests between accounts by using services such as AWS Transit Gateway, and control them using AWS Network Firewall.

There are always trade-offs between complexity, convenience, and security, so the right level of isolation between components depends on your requirements.

Perimeter 4 – the load balancer

After the request is sent to the VPC, an Application Load Balancer (ALB) processes it. The ALB distributes requests to the underlying EC2 instances. The ALB uses TLS version 1.2 to encrypt incoming connections with an AWS Certificate Manager (ACM) certificate.

Public access to the load balancer isn’t allowed. A security group applied to the ALB only allows inbound traffic on port 443 from the CloudFront IP range. This is achieved by specifying the Region-specific AWS-managed CloudFront prefix list as the source in the security group rule.

The ALB uses rules to decide whether to forward the request to the target instances or reject the traffic. As an additional layer of security, it uses the custom headers that the CloudFront distribution added to make sure that the request is from CloudFront. In another rule, the ALB uses the originating user’s IP to decide which target group of Amazon EC2 instances should handle the request. In this way, you can direct admin users to instances that are configured to allow admin tasks.

If a request doesn’t match a valid rule, the ALB returns a 404 response to the user.

Perimeter 5 – compute instance network security

A security group creates an isolation boundary around the EC2 instances. The only traffic that reaches the instance is the traffic that the security group rules allow. In this solution, only the ALB is allowed to make inbound connections to the EC2 instances.

A common practice is for customers to also open ports, or to set up and manage bastion hosts to provide remote access to their compute instances. The risk in this approach is that the ports could be left open to the whole internet, exposing the instances to vulnerabilities in the remote access protocol. With remote work on the rise, there is an increased risk for the creation of these overly permissive inbound rules.

Using AWS Systems Manager Session Manager, you can remove the need for bastion hosts or open ports by creating secure temporary connections to your EC2 instances using the installed SSM agent. As with every software package that you install, you should check that the SSM agent aligns with your security and compliance requirements. To review the source code to the SSM agent, see amazon-ssm-agent GitHub repo.

The compute layer of this solution consists of two separate Amazon EC2 Auto Scaling groups of EC2 instances. One group handles requests from administrators, while the other handles requests from unprivileged users. This creates another isolation boundary by keeping the functions separate while also helping to protect the system from a failure in one component causing the whole system to fail. Each Amazon EC2 Auto Scaling group spans multiple Availability Zones (AZs), providing resilience in the event of an outage in an AZ.

By using managed database services, you can reduce the risk that database server instances haven’t been proactively patched for security updates. Managed infrastructure helps reduce the risk of security issues that result from the underlying operating system not receiving security patches in a timely manner and the risk of downtime from hardware failures.

Perimeter 6 – compute instance operating system

When instances are first launched, the operating system must be secure, and the instances must be updated as required when new security patches are released. We recommend that you create immutable servers that you build and harden by using a tool such as EC2 Image Builder. Instead of patching running instances in place, replace them when an updated Amazon Machine Image (AMI) is created. This approach works in our example scenario because the application code (which changes over time) is stored on Amazon Elastic File System (Amazon EFS), so when you replace the instances with a new AMI, you don’t need to update them with data that has changed after the initial deployment.

Another way that the solution helps improve security on your instances at the operating system is to use EC2 instance profiles to allow them to assume IAM roles. IAM roles grant temporary credentials to applications running on EC2, instead of using hard-coded credentials stored on the instance. Access to other AWS resources is provided using these temporary credentials.

The IAM roles have least privilege policies attached that grant permission to mount the EFS file system and access AWS Systems Manager. If a database secret exists in Secrets Manager, the IAM role is granted permission to access it.

Perimeter 7 – at the file system

Both Amazon EC2 Auto Scaling groups of EC2 instances share access to Amazon EFS, which hosts the files that the application uses. IAM authorization applies IAM file system policies to control the instance’s access to the file system. This creates another isolation boundary that helps prevent the non-admin instances from modifying the application’s files.

The admin group’s instances have the file system mounted in read-write mode. This is necessary so that the application can update itself, install add-ons, upload content, or make configuration changes. On the unprivileged instances, the file system is mounted in read-only mode. This means that these instances can’t make changes to the application code or configuration files.

The unprivileged instances have local file caching enabled. This caches files from the EFS file system on the local Amazon Elastic Block Store (Amazon EBS) volume to help improve scalability and performance.

Perimeter 8 – web server configuration

This solution applies different web server configurations to the instances running in each Amazon EC2 Auto Scaling group. This creates a further isolation boundary at the web server layer.

The admin instances use the default configuration for the application that permits access to the admin interface. Non-admin, public-facing instances block admin routes, such as wp-login.php, and will return a 403 Forbidden response. This creates an additional layer of protection for those routes.

Perimeter 9 – database security

The database layer is within two additional isolation boundaries. The solution uses Amazon RDS, with database instances deployed in isolated subnets. Isolated subnets have no inbound or outbound internet access and can only be reached through other network interfaces within the VPC. The RDS security group further isolates the database instances by only allowing inbound traffic from the EC2 instances on the database server port.

By using IAM authentication for the database access, you can add an additional layer of security by configuring the non-admin instances with less privileged database user credentials.

Perimeter 10 – Security at the application code layer

To apply security at the application code level, you should establish good practices around installing updates as they become available. Most applications have email lists that you can subscribe to that will notify you when updates become available.

You should evaluate the quality of an application before you adopt it. The following are some metrics to consider:

  • Number of developers who are actively working on it
  • Frequency of updates to it
  • How quickly the developers respond with patches when bugs are reported

Other steps that you can take

Use AWS Verified Access to help secure application access for human users. With Verified Access, you can add another user authentication stage, to help ensure that only verified users can access an application’s administrative functions.

Amazon GuardDuty is a threat detection service that continuously monitors your AWS accounts and workloads for malicious activity and delivers detailed security findings for visibility and remediation. It can detect communication with known malicious domains and IP addresses and identify anomalous behavior. GuardDuty Malware Protection helps you detect the potential presence of malware by scanning the EBS volumes that are attached to your EC2 instances.

Amazon Inspector is an automated vulnerability management service that automatically discovers the Amazon EC2 instances that are running and scans them for software vulnerabilities and unintended network exposure. To help ensure that your web server instances are updated when security patches are available, use AWS Systems Manager Patch Manager.

Deploy the sample project

We wrote the Run Web-Administered Apps on AWS project by using the AWS Cloud Development Kit (AWS CDK). With the AWS CDK, you can use the expressive power of familiar programming languages to define your application resources and accelerate development. The AWS CDK has support for multiple languages, including TypeScript, Python, .NET, Java, and Go.

This project uses Python. To deploy it, you need to have a working version of Python 3 on your computer. For instructions on how to install the AWS CDK, see Get Started with AWS CDK.

Configure the project

To enable this project to deploy multiple different web projects, you must do the configuration in the parameters.properties file. Two variables identify the configuration blocks: app (which identifies the web application to deploy) and env (which identifies whether the deployment is to a dev or test environment, or to production).

When you deploy the stacks, you specify the app and env variables as CDK context variables so that you can select between different configurations at deploy time. If you don’t specify a context, a [default] stanza in the parameters.properties file specifies the default app name and environment that will be deployed.

To name other stanzas, combine valid app and env values by using the format <app>-<env>. For each stanza, you can specify its own Regions, accounts, instance types, instance counts, hostnames, and more. For example, if you want to support three different WordPress deployments, you might specify the app name as wp, and for env, you might want dev, test, and prod, giving you three stanzas: wp-dev, wp-test, and wp-prod.

The project includes sample configuration items that are annotated with comments that explain their function.

Use CDK bootstrapping

Before you can use the AWS CDK to deploy stacks into your account, you need to use CDK bootstrapping to provision resources in each AWS environment (account and Region combination) that you plan to use. For this project, you need to bootstrap both the US East (N. Virginia) Region (us-east-1)  and the home Region in which you plan to host your application.

Create a hosted zone in the target account

You need to have a hosted zone in Route 53 to allow the creation of DNS records and certificates. You must manually create the hosted zone by using the AWS Management Console. You can delegate a domain that you control to Route 53 and use it with this project. You can also register a domain through Route 53 if you don’t currently have one.

Run the project

Clone the project to your local machine and navigate to the project root. To create the Python virtual environment (venv) and install the dependencies, follow the steps in the Generic CDK instructions.

To create and configure the parameters.properties file

Copy the parameters-template.properties file (in the root folder of the project) to a file called parameters.properties and save it in the root folder. Open it with a text editor and then do the following:

If you want to restrict public access to your site, change 192.0.2.0/24 to the IP range that you want to allow. By providing a comma-separated list of allowedIps, you can add multiple allowed CIDR blocks.

If you don’t want to restrict public access, set allowedIps=* instead.

If you have forked this project into your own private repository, you can commit the parameters.properties file to your repo. To do that, comment out the parameters.properties  line in the .gitignore file.

To install the custom resource helper

The solution uses an AWS CloudFormation custom resource for cross-Region configuration management. To install the needed Python package, run the following command in the custom_resource directory:

cd custom_resource
pip install crhelper -t .

To learn more about CloudFormation custom resource creation, see AWS CloudFormation custom resource creation with Python, AWS Lambda, and crhelper.

To configure the database layer

Before you deploy the stacks, decide whether you want to include a data layer as part of the deployment. The dbConfig parameter determines what will happen, as follows:

  • If dbConfig is left empty — no database will be created and no database credentials will be available in your compute stacks
  • If dbConfig is set to instance — you will get a new Amazon RDS instance
  • If dbConfig is set to cluster — you will get an Amazon Aurora cluster
  • If dbConfig is set to none — if you previously created a database in this stack, the database will be deleted

If you specify either instance or cluster, you should also configure the following database parameters to match your requirements:

  • dbEngine — set the database engine to either mysql or postgres
  • dbSnapshot — specify the named snapshot for your database
  • dbSecret — if you are using an existing database, specify the Amazon Resource Name (ARN) of the secret where the database credentials and DNS endpoint are located
  • dbMajorVersion — set the major version of the engine that you have chosen; leave blank to get the default version
  • dbFullVersion — set the minor version of the engine that you have chosen; leave blank to get the default version
  • dbInstanceType — set the instance type that you want (note that these vary by service); don’t prefix with db. because the CDK will automatically prepend it
  • dbClusterSize — if you request a cluster, set this parameter to determine how many Amazon Aurora replicas are created

You can choose between mysql or postgres for the database engine. Other settings that you can choose are determined by that choice.

You will need to use an Amazon Machine Image (AMI) that has the CLI preinstalled, such as Amazon Linux 2, or install the AWS Command Line Interface (AWS CLI) yourself with a user data command. If instead of creating a new, empty database, you want to create one from a snapshot, supply the snapshot name by using the dbSnapshot parameter.

To create the database secret

AWS automatically creates and stores the RDS instance or Aurora cluster credentials in a Secrets Manager secret when you create a new instance or cluster. You make these credentials available to the compute stack through the db_secret_command variable, which contains a single-line bash command that returns the JSON from the AWS CLI command aws secretsmanager get-secret-value. You can interpolate this variable into your user data commands as follows:

SECRET=$({db_secret_command})
USERNAME=`echo $SECRET | jq -r '.username'`
PASSWORD=`echo $SECRET | jq -r '.password'`
DBNAME=`echo $SECRET | jq -r '.dbname'`
HOST=`echo $SECRET | jq -r '.host'`

If you create a database from a snapshot, make sure that your Secrets Manager secret and Amazon RDS snapshot are in the target Region. If you supply the secret for an existing database, make sure that the secret contains at least the following four key-value pairs (replace the <placeholder values> with your values):

{
    "password":"<your-password>",
    "dbname":"<your-database-name>",
    "host":"<your-hostname>",
    "username":"<your-username>"
}

The name for the secret must match the app value followed by the env value (both in title case), followed by DatabaseSecret, so for app=wp and env=dev, your secret name should be WpDevDatabaseSecret.

To deploy the stacks

The following commands deploy the stacks defined in the CDK app. To deploy them individually, use the specific stack names (these will vary according to the info that you supplied previously), as shown in the following.

cdk deploy wp-dev-network-stack -c app=wp -c env=dev
cdk deploy wp-dev-database-stack -c app=wp -c env=dev
cdk deploy wp-dev-compute-stack -c app=wp -c env=dev
cdk deploy wp-dev-cdn-stack -c app=wp -c env=dev

To create a database stack, deploy the network and database stacks first.

cdk deploy wp-dev-network-stack -c app=wp -c env=dev
cdk deploy wp-dev-database-stack -c app=wp -c env=dev

You can then initiate the deployment of the compute stack.

cdk deploy wp-dev-compute-stack -c app=wp -c env=dev

After the compute stack deploys, you can deploy the stack that creates the CloudFront distribution.

cdk deploy wp-dev-cdn-stack -c env=dev

This deploys the CloudFront infrastructure to the US East (N. Virginia) Region (us-east-1). CloudFront is a global AWS service, which means that you must create it in this Region. The other stacks are deployed to the Region that you specified in your configuration stanza.

To test the results

If your stacks deploy successfully, your site appears at one of the following URLs:

  • subdomain.hostedZone (if you specified a value for the subdomain) — for example, www.example.com
  • appName-env.hostedZone (if you didn’t specify a value for the subdomain) — for example, wp-dev.example.com.

If you connect through the IP address that you configured in the adminIps configuration, you should be connected to the admin instance for your site. Because the admin instance can modify the file system, you should use it to do your administrative tasks.

Users who connect to your site from an IP that isn’t in your allowedIps list will be connected to your fleet instances and won’t be able to alter the file system (for example, they won’t be able to install plugins or upload media).

If you need to redeploy the same app-env combination, manually remove the parameter store items and the replicated secret that you created in us-east-1. You should also delete the cdk.context.json file because it caches values that you will be replacing.

One project, multiple configurations

You can modify the configuration file in this project to deploy different applications to different environments using the same project. Each app can have different configurations for dev, test, or production environments.

Using this mechanism, you can deploy sites for test and production into different accounts or even different Regions. The solution uses CDK context variables as command-line switches to select different configuration stanzas from the configuration file.

CDK projects allow for multiple deployments to coexist in one account by using unique names for the deployed stacks, based on their configuration.

Check the configuration file into your source control repo so that you track changes made to it over time.

Got a different web app that you want to deploy? Create a new configuration by copying and pasting one of the examples and then modify the build commands as needed for your use case.

Conclusion

In this post, you learned how to build an architecture on AWS that implements multi-layered security. You can use different AWS services to provide protections to your application at different stages of the request lifecycle.

You can learn more about the services used in this sample project by building it in your own account. It’s a great way to explore how the different services work and the full features that are available. By understanding how these AWS services work, you will be ready to use them to add security, at multiple layers, in your own architectures.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Guy Morton

Guy Morton

Guy is a Senior Solutions Architect at AWS. He enjoys bringing his decades of experience as a full stack developer, architect, and people manager to helping customers build and scale their applications securely in the AWS Cloud. Guy has a passion for automation in all its forms, and is also an occasional songwriter and musician who performs under the pseudonym Whtsqr.

Your DevOps and Developer Productivity guide to re:Invent 2023

Post Syndicated from Anubhav Rao original https://aws.amazon.com/blogs/devops/your-devops-and-developer-productivity-guide-to-reinvent-2023/

Your DevOps and Developer Productivity guide to re:Invent 2023

ICYMI – AWS re:Invent is less than a week away! We can’t wait to join thousands of builders in person and virtually for another exciting event. Still need to save your spot? You can register here.

With so much planned for the DevOps and Developer Productivity (DOP) track at re:Invent, we’re highlighting the most exciting sessions for technology leaders and developers in this post. Sessions span intermediate (200) through expert (400) levels of content in a mix of interactive chalk talks, hands-on workshops, and lecture-style breakout sessions.

You will experience the future of efficient development at the DevOps and Developer Productivity track and get a chance to talk to AWS experts about exciting services, tools, and new AI capabilities that optimize and automate your software development lifecycle. Attendees will leave re:Invent with the latest strategies to accelerate development, use generative AI to improve developer productivity, and focus on high-value work and innovation.

How to reserve a seat in the sessions

Reserved seating is available for registered attendees to secure seats in the sessions of their choice. Reserve a seat by signing in to the attendee portal and navigating to Event, then Sessions.

Do not miss the Innovation Talk led by Vice President of AWS Generative Builders, Adam Seligman. In DOP225-INT Build without limits: The next-generation developer experience at AWS, Adam will provide updates on the latest developer tools and services, including generative AI-powered capabilities, low-code abstractions, cloud development, and operations. He’ll also welcome special guests to lead demos of key developer services and showcase how they integrate to increase productivity and innovation.

DevOps and Developer Productivity breakout sessions

What are breakout sessions?

AWS re:Invent breakout sessions are lecture-style and 60 minutes long. These sessions are delivered by AWS experts and typically reserve 10–15 minutes for Q&A at the end. Breakout sessions are recorded and made available on-demand after the event.

Level 200 — Intermediate

DOP201 | Best practices for Amazon CodeWhisperer Generative AI can create new content and ideas, including conversations, stories, images, videos, and music. Learning how to interact with generative AI effectively and proficiently is a skill worth developing. Join this session to learn about best practices for engaging with Amazon CodeWhisperer, which uses an underlying foundation model to radically improve developer productivity by generating code suggestions in real time.

DOP202 | Realizing the developer productivity benefits of Amazon CodeWhisperer Developers spend a significant amount of their time writing undifferentiated code. Amazon CodeWhisperer radically improves productivity by generating code suggestions in real time to alleviate this burden. In this session, learn how CodeWhisperer can “write” much of this undifferentiated code, allowing developers to focus on business logic and accelerate the pace of their innovation.

DOP205 | Accelerate development with Amazon CodeCatalyst In this session, explore the newest features in Amazon CodeCatalyst. Learn firsthand how these practical additions to CodeCatalyst can simplify application delivery, improve team collaboration, and speed up the software development lifecycle from concept to deployment.

DOP206 | AWS infrastructure as code: A year in review AWS provides services that help with the creation, deployment, and maintenance of application infrastructure in a programmatic, descriptive, and declarative way. These services help provide rigor, clarity, and reliability to application development. Join this session to learn about the new features and improvements for AWS infrastructure as code with AWS CloudFormation and AWS Cloud Development Kit (AWS CDK) and how they can benefit your team.

DOP207 | Build and run it: Streamline DevOps with machine learning on AWS While organizations have improved how they deliver and operate software, development teams still run into issues when performing manual code reviews, looking for hard-to-find defects, and uncovering security-related problems. Developers have to keep up with multiple programming languages and frameworks, and their productivity can be impaired when they have to search online for code snippets. Additionally, they require expertise in observability to successfully operate the applications they build. In this session, learn how companies like Fidelity Investments use machine learning–powered tools like Amazon CodeWhisperer and Amazon DevOps Guru to boost application availability and write software faster and more reliably.

DOP208 | Continuous integration and delivery for AWS AWS provides one place where you can plan work, collaborate on code, build, test, and deploy applications with continuous integration/continuous delivery (CI/CD) tools. In this session, learn about how to create end-to-end CI/CD pipelines using infrastructure as code on AWS.

DOP209 | Governance and security with infrastructure as code In this session, learn how to use AWS CloudFormation and the AWS CDK to deploy cloud applications in regulated environments while enforcing security controls. Find out how to catch issues early with cdk-nag, validate your pipelines with cfn-guard, and protect your accounts from unintended changes with CloudFormation hooks.

DOP210 | Scale your application development with Amazon CodeCatalyst Amazon CodeCatalyst brings together everything you need to build, deploy, and collaborate on software into one integrated software development service. In this session, discover the ways that CodeCatalyst helps developers and teams build and ship code faster while spending more time doing the work they love.

DOP211 | Boost developer productivity with Amazon CodeWhisperer Generative AI is transforming the way that developers work. Writing code is already getting disrupted by tools like Amazon CodeWhisperer, which enhances developer productivity by providing real-time code completions based on natural language prompts. In this session, get insights into how to evaluate and measure productivity with the adoption of generative AI–powered tools. Learn from the AWS Disaster Recovery team who uses CodeWhisperer to solve complex engineering problems by gaining efficiency through longer productivity cycles and increasing velocity to market for ongoing fixes. Hear how integrating tools like CodeWhisperer into your workflows can boost productivity.

DOP212 | New AWS generative AI features and tools for developers Explore how generative AI coding tools are changing the way developers and companies build software. Generative AI–powered tools are boosting developer and business productivity by automating tasks, improving communication and collaboration, and providing insights that can inform better decision-making. In this session, see the newest AWS tools and features that make it easier for builders to solve problems with minimal technical expertise and that help technical teams boost productivity. Walk through how organizations like FINRA are exploring generative AI and beginning their journey using these tools to accelerate their pace of innovation.

DOP220 | Simplify building applications with AWS SDKs AWS SDKs play a vital role in using AWS services in your organization’s applications and services. In this session, learn about the current state and the future of AWS SDKs. Explore how they can simplify your developer experience and unlock new capabilities. Discover how SDKs are evolving, providing a consistent experience in multiple languages and empowering you to do more with high-level abstractions to make it easier to build on AWS. Learn how AWS SDKs are built using open source tools like Smithy, and how you can use these tools to build your own SDKs to serve your customers’ needs.

DevOps and Developer Productivity chalk talks

What are chalk talks?

Chalk Talks are highly interactive sessions with a small audience. Experts lead you through problems and solutions on a digital whiteboard as the discussion unfolds. Each begins with a short lecture (10–15 minutes) delivered by an AWS expert, followed by a 45- or 50-minute Q&A session with the audience.

Level 300 — Advanced

DOP306 | Streamline DevSecOps with a complete software development service Security is not just for application code—the automated software supply chains that build modern software can also be exploited by attackers. In this chalk talk, learn how you can use Amazon CodeCatalyst to incorporate security tests into every aspect of your software development lifecycle while maintaining a great developer experience. Discover how CodeCatalyst’s flexible actions-based CI/CD workflows streamline the process of adapting to security threats.

DOP309-R | AI for DevOps: Modernizing your DevOps operations with AWS As more organizations move to microservices architectures to scale their businesses, applications increasingly have become distributed, requiring the need for even greater visibility. IT operations professionals and developers need more automated practices to maintain application availability and reduce the time and effort required to detect, debug, and resolve operational issues. In this chalk talk, discover how you can use AWS services, including Amazon CodeWhisperer, Amazon CodeGuru and Amazon DevOps Guru, to start using AI for DevOps solutions to detect, diagnose, and remedy anomalous application behavior.

DOP310-R | Better together: GitHub Actions, Amazon CodeCatalyst, or AWS CodeBuild Learn how combining GitHub Actions with Amazon CodeCatalyst or AWS CodeBuild can maximize development efficiency. In this chalk talk, learn about the tradeoffs of using GitHub Actions runners hosted on Amazon EC2 or Amazon ECS with GitHub Actions hosted on CodeCatalyst or CodeBuild. Explore integration with other AWS services to enhance workflow automation. Join this talk to learn how GitHub Actions on AWS can take your development processes to the next level.

DOP311 | Building infrastructure as code with AWS CloudFormation AWS CloudFormation helps you manage your AWS infrastructure as code, increasing automation and supporting infrastructure-as-code best practices. In this chalk talk, learn the fundamentals of CloudFormation, including templates, stacks, change sets, and stack dependencies. See a demo of how to describe your AWS infrastructure in a template format and provision resources in an automated, repeatable way.

DOP312 | Creating custom constructs with AWS CDK Join this chalk talk to get answers to your questions about creating, publishing, and sharing your AWS CDK constructs publicly and privately. Learn about construct levels, how to test your constructs, how to discover and use constructs in your AWS CDK projects, and explore Construct Hub.

DOP313-R | Multi-account and multi-Region deployments at scale Many AWS customers are implementing multi-account strategies to more easily manage their cloud infrastructure and improve their security and compliance postures. In this chalk talk, learn about various options for deploying resources into multiple accounts and AWS Regions using AWS developer tools, including AWS CodePipeline, AWS CodeDeploy, and Amazon CodeCatalyst.

DOP314 | Simplifying cloud infrastructure creation with the AWS CDK The AWS Cloud Development Kit (AWS CDK) is an open source software development framework for defining cloud infrastructure in code and provisioning it through AWS CloudFormation. In this chalk talk, get an introduction to the AWS CDK and see a demo of how it can simplify infrastructure creation. Through code examples and diagrams, see how the AWS CDK lets you use familiar programming languages for declarative infrastructure definition. Also learn how it provides higher-level abstractions and constructs over native CloudFormation.

DOP317 | Applying Amazon’s DevOps culture to your team In this chalk talk, learn how Amazon helps its developers rapidly release and iterate software while maintaining industry-leading standards on security, reliability, and performance. Learn about the culture of two-pizza teams and how to maintain a culture of DevOps in a large enterprise. Also, discover how you can help build such a culture at your own organization.

DOP318 | Testing for resilience with AWS Fault Injection Simulator As cloud-based systems grow in scale and complexity, there is increased need to test distributed systems for resiliency. AWS Fault Injection Simulator (FIS) allows you to stress test your applications to understand failure modes and build more resilient services. Through code examples and diagrams, see how to set up and run fault injection experiments on AWS. By the end of this session, understand how FIS helps identify weaknesses and validate improvements to build more resilient cloud-based systems.

DOP319-R | Zero-downtime deployment strategies AWS services support a wealth of deployment options to meet your needs, ranging from in-place updates to blue/green deployment to continuous configuration with feature flags. In this chalk talk, hear about multiple options for deploying changes to Amazon EC2, Amazon ECS, and AWS Lambda compute platforms using AWS CodeDeploy, AWS AppConfig, AWS CloudFormation, AWS Cloud Development Kit (AWS CDK), and Amazon CodeCatalyst.

DOP320 | Build a path to production with Amazon CodeCatalyst blueprints Amazon CodeCatalyst uses blueprints to configure your software projects in the service. Blueprints instruct CodeCatalyst on how to set up a code repository with working sample code, define cloud infrastructure, and run pre-configured CI/CD workflows for your project. In this session, learn how blueprints in CodeCatalyst can give developers a compliant software service they’ll want to use on AWS.

DOP321-R | Code faster with Amazon CodeWhisperer Traditionally, building applications requires developers to spend a lot of time manually writing code and trying to learn and keep up with new frameworks, SDKs, and libraries. In the last three years, AI models have grown exponentially in complexity and sophistication, enabling the creation of tools like Amazon CodeWhisperer that can generate code suggestions in real time based on a natural language description of the task. In this session, learn how CodeWhisperer can accelerate and enhance your software development with code generation, reference tracking, security scans, and more.

DOP324 | Accelerating application development with AWS client-side tools Did you know AWS has more than just services? There are dozens of AWS client-side tools and libraries designed to make developing quality applications easier. In this chalk talk, explore some of the tools available in your development workspace. Learn more about command line tooling (AWS CLI), libraries (AWS SDK), IDE integrations, and application frameworks that can accelerate your AWS application development. The audience helps set the agenda so there’s sure to be something for every builder.

DevOps and Developer Productivity workshops

What are workshops?

Workshops are two-hour interactive learning sessions where you work in small group teams to solve problems using AWS services. Each workshop starts with a short lecture (10–15 minutes) by the main speaker, and the rest of the time is spent working as a group.

Level 300 — Advanced

DOP301 | Boost your application availability with AIOps on AWS As applications become increasingly distributed and complex, developers and IT operations teams can benefit from more automated practices to maintain application availability and reduce the time and effort spent detecting, debugging, and resolving operational issues manually. In this workshop, learn how AWS AIOps solutions can help you make the shift toward more automation and proactive mechanisms so your IT team can innovate faster. The workshop includes use cases spanning multiple AWS services such as AWS Lambda, Amazon DynamoDB, Amazon API Gateway, Amazon RDS, and Amazon EKS. Learn how you can reduce MTTR and quickly identify issues within your AWS infrastructure. You must bring your laptop to participate.

DOP302 | Build software faster with Amazon CodeCatalyst In this workshop, learn about creating continuous integration and continuous delivery (CI/CD) pipelines using Amazon CodeCatalyst. CodeCatalyst is a unified software development service on AWS that brings together everything teams need to plan, code, build, test, and deploy applications with continuous CI/CD tools. You can utilize AWS services and integrate AWS resources into your projects by connecting your AWS accounts. With all of the stages of an application’s lifecycle in one tool, you can deliver quality software quickly and confidently. You must bring your laptop to participate.

DOP303-R | Continuous integration and delivery on AWS In this workshop, learn to create end-to-end continuous integration and continuous delivery (CI/CD) pipelines using AWS Cloud Development Kit (AWS CDK). Review the fundamental concepts of continuous integration, continuous deployment, and continuous delivery. Then, using TypeScript/Python, define an AWS CodePipeline, AWS CodeBuild, and AWS CodeCommit workflow. You must bring your laptop to participate.

DOP304 | Develop AWS CDK resources to deploy your applications on AWS In this workshop, learn how to build and deploy applications using infrastructure as code with AWS Cloud Development Kit (AWS CDK). Create resources using AWS CDK and learn maintenance and operations tips. In addition, get an introduction to building your own constructs. You must bring your laptop to participate.

DOP305 | Develop AWS CloudFormation templates to manage your infrastructure In this workshop, learn how to develop and test AWS CloudFormation templates. Create CloudFormation templates to deploy and manage resources and learn about CloudFormation language features that allow you to reuse and extend templates for many scenarios. Explore testing tools that can help you validate your CloudFormation templates, including cfn-lint and CloudFormation Guard. You must bring your laptop to participate.

DOP307-R | Hands-on with Amazon CodeWhisperer In this workshop, learn how to build applications faster and more securely with Amazon CodeWhisperer. The workshop begins with several examples highlighting how CodeWhisperer incorporates your comments and existing code to produce results. Then dive into a series of challenges designed to improve your productivity using multiple languages and frameworks. You must bring your laptop to participate.

DOP308 | Enforcing development standards with Amazon CodeCatalyst In this workshop, learn how Amazon CodeCatalyst can accelerate the application development lifecycle within your organization. Discover how your cloud center of excellence (CCoE) can provide standardized code and workflows to help teams get started quickly and securely. In addition, learn how to update projects as organization standards evolve. You must bring your laptop to participate.

Level 400 — Expert

DOP401 | Get better at building AWS CDK constructs In this workshop, dive deep into how to design AWS CDK constructs, which are reusable and shareable cloud components that help you meet your organization’s security, compliance, and governance requirements. Learn how to build, test, and share constructs representing a single AWS resource, as well as how to create higher-level abstractions that include built-in defaults and allow you to provision multiple AWS resources. You must bring your laptop to participate.

DevOps and Developer Productivity builders’ sessions

What are builders’ sessions?

These 60-minute group sessions are led by an AWS expert and provide an interactive learning experience for building on AWS. Builders’ sessions are designed to create a hands-on experience where questions are encouraged.

Level 300 — Advanced

DOP322-R | Accelerate data science coding with Amazon CodeWhisperer Generative AI removes the heavy lifting that developers experience today by writing much of the undifferentiated code, allowing them to build faster. Helping developers code faster could be one of the most powerful uses of generative AI that we will see in the coming years—and this framework can also be applied to data science projects. In this builders’ session, explore how Amazon CodeWhisperer accelerates the completion of data science coding tasks with extensions for JupyterLab and Amazon SageMaker. Learn how to build data processing pipeline and machine learning models with the help of CodeWhisperer and accelerate data science experiments in Python. You must bring your laptop to participate.

Level 400 — Expert

DOP402-R | Manage dev environments at scale with Amazon CodeCatalyst Amazon CodeCatalyst Dev Environments are cloud-based environments that you can use to quickly work on the code stored in the source repositories of your project. They are automatically created with pre-installed dependencies and language-specific packages so you can work on a new or existing project right away. In this session, learn how to create secure, reproducible, and consistent environments for VS Code, AWS Cloud9, and JetBrains IDEs. You must bring your laptop to participate.

DOP403-R | Hands-on with Amazon CodeCatalyst: Automating security in CI/CD pipelines In this session, learn how to build a CI/CD pipeline with Amazon CodeCatalyst and add the necessary steps to secure your pipeline. Learn how to perform tasks such as secret scanning, software composition analysis (SCA), static application security testing (SAST), and generating a software bill of materials (SBOM). You must bring your laptop to participate.

DevOps and Developer Productivity lightning talks

What are lightning talks?

Lightning talks are short, 20-minute demos led from a stage.

DOP221 | Amazon CodeCatalyst in real time: Deploying to production in minutes In this follow-up demonstration to DOP210, see how you can use an Amazon CodeCatalyst blueprint to build a production-ready application that is set up for long-term success. See in real time how to create a project using a CodeCatalyst Dev Environment and deploy it to production using a CodeCatalyst workflow.

DevOps and Developer Productivity code talks

What are code talks?

Code talks are 60-minute, highly-interactive discussions featuring live coding. Attendees are encouraged to dig in and ask questions about the speaker’s approach.

DOP203 | The future of development on AWS This code talk includes a live demo and an open discussion about how builders can use the latest AWS developer tools and generative AI to build production-ready applications in minutes. Starting at an Amazon CodeCatalyst blueprint and using integrated AWS productivity and security capabilities, see a glimpse of what the future holds for developing on AWS.

DOP204 | Tips and tricks for coding with Amazon CodeWhisperer Generative AI tools that can generate code suggestions, such as Amazon CodeWhisperer, are growing rapidly in popularity. Join this code talk to learn how CodeWhisperer can accelerate and enhance your software development with code generation, reference tracking, security scans, and more. Learn best practices for prompt engineering, and get tips and tricks that can help you be more productive when building applications.

Want to stay connected?

Get the latest updates for DevOps and Developer Productivity by following us on Twitter and visiting the AWS devops blog.

Establishing a data perimeter on AWS: Require services to be created only within expected networks

Post Syndicated from Harsha Sharma original https://aws.amazon.com/blogs/security/establishing-a-data-perimeter-on-aws-require-services-to-be-created-only-within-expected-networks/

Welcome to the fifth post in the Establishing a data perimeter on AWS series. Throughout this series, we’ve discussed how a set of preventative guardrails can create an always-on boundary to help ensure that your trusted identities are accessing your trusted resources over expected networks. In a previous post, we emphasized the importance of preventing access from unexpected locations, even for authorized users. For example, you wouldn’t expect non-public corporate data to be accessed from outside the corporate network. In this post, we demonstrate how to use preventative controls to help ensure that your resources are deployed within your Amazon Virtual Private Cloud (Amazon VPC), so that you can effectively enforce the network perimeter controls. We also explore detective controls you can use to detect the lack of adherence to this requirement.

Let’s begin with a quick refresher on the fundamental concept of data perimeters using Figure 1 as a reference. Customers generally prefer establishing a high-level perimeter to help prevent untrusted entities from coming in and data from going out. The perimeter defines what access customers expect within their AWS environment. It refers to the access patterns among your identities, resources, and networks that should always be blocked. Using those three elements, an assertion can be made to define your perimeter’s goal: access can only be allowed if the identity is trusted, the resource is trusted, and the network is expected. If any of these conditions are false, then the access inside the perimeter is unintended and should be denied. The perimeter is composed of controls implemented on your identities, resources, and networks to maintain that the necessary conditions are true.

Figure 1: A high-level depiction of defining a perimeter around your AWS resources to prevent interaction with unintended IAM principals, unintended resources, and unexpected networks

Figure 1: A high-level depiction of defining a perimeter around your AWS resources to prevent interaction with unintended IAM principals, unintended resources, and unexpected networks

Now, let’s consider a scenario to understand the problem statement this post is trying to solve. Assume a setup like the one in Figure 2, where an application needs to access an Amazon Simple Storage Service (Amazon S3) bucket using its temporary AWS Identity and Access Management (IAM) credentials over an Amazon S3 VPC endpoint.

Figure 2: Scenario of a simple app using its temporary credential to access an S3 bucket

Figure 2: Scenario of a simple app using its temporary credential to access an S3 bucket

From our previous posts in this series, we’ve learned that we can use the following set of capabilities to build a network perimeter to achieve our control objectives for this sample scenario.

Control objective Implemented using Applicable IAM capability
My identities can access resources only from expected networks. For example, in Figure 2, my application’s temporary credential can only access my S3 bucket when my application is within my expected network space. Service control policies (SCP) aws:SourceIp
aws:SourceVpc
aws:SourceVpce
My resources can only be accessed from expected networks. For example, in Figure 2, my S3 bucket can only be accessed from my expected network space. Resource-based policies aws:SourceIp
aws:SourceVpc
aws:SourceVpce

But there are certain AWS services that allow for different network deployment models, such as providing the choice of associating the service resources with either an AWS managed VPC or a customer managed VPC. For example, an AWS Lambda function always runs inside a VPC owned by the Lambda service (AWS managed VPC) and by default isn’t connected to VPCs in your account (customer managed VPC). For more information, see Connecting Lambda functions to your VPC.

This means that if your application code was deployed as a Lambda function that isn’t connected to your VPC, then the function cannot access your resources with standard network perimeter controls enforced. Let’s understand this situation better using Figure 3, where a Lambda function isn’t configured to connect to the customer VPC. This function cannot access your S3 bucket over the internet because of how the recommended data perimeter in the preceding table has been defined, that is, to only allow your bucket to be accessible from a known network segment (the customer VPC and IP CIDR range) and only allow the IAM role associated with the Lambda function to allow accessing the bucket from known networks. The function also cannot access your S3 bucket through your S3 VPC endpoint because the function isn’t associated with the customer VPC. Lastly, unless other compensating controls are in place, this function might be able to access untrusted resources as your standard data perimeter controls enforced with the VPC endpoint policies won’t be in effect, which might not meet your company’s security requirements.

Figure 3: Lambda function configured to be associated with AWS managed VPC

Figure 3: Lambda function configured to be associated with AWS managed VPC

This means that for the Lambda function to conform to your data perimeter, it must be associated with your network segment (customer VPC) as shown in Figure 4.

Figure 4: Lambda function configured to be associated with the customer managed VPC

Figure 4: Lambda function configured to be associated with the customer managed VPC

To make sure that your Lambda functions are deployed into your networks so that they can access your resources under the purview of data perimeter controls, it’s preferable to have a way to automatically prevent deployment or configuration errors. Additionally, if you have a large deployment of Lambda functions across hundreds or even thousands of accounts, you want an efficient way to enforce conformance of these functions to your data perimeter.

To solve for this problem and make sure that an application team or a developer cannot create a function that’s not associated with your VPC, you can use the lambda:VpcIds or lambda:SubnetIds IAM condition keys (for more information, see Using IAM condition keys for VPC settings). These keys allow you to create and update functions only when VPC settings are satisfied.

In the following SCP example, an IAM principal that is subject to the following SCP policy will only be able to create or update a Lambda function if the function is associated with a VPC (customer VPC). When the customer VPC isn’t specified, the lambda:VpcIds condition key has no value—it is null—and thus this policy will deny creating or updating the function. For more information about how the Null condition operator functions, see Condition operator to check existence of condition keys.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "EnforceVPCFunction",
      "Action": [
          "lambda:CreateFunction",
          "lambda:UpdateFunctionConfiguration"
       ],
      "Effect": "Deny",
      "Resource": "*",
      "Condition": {
        "Null": {
           "lambda:VpcIds": "true"
        }
      }
    }
  ]
}

Additionally, you can use variations of the preceding example and create more fine-grained controls using these condition keys. For more such examples, see Example policies with condition keys for VPC settings.

AWS services such as AWS Glue and Amazon SageMaker have similar feature behavior and provide similar condition keys. For example, the glue:VpcIds condition key allows you to govern the creation of AWS Glue jobs only in your VPC. For further details and an example policy, see Control policies that control settings using condition keys.

Similarly, Amazon SageMaker Studio, SageMaker notebook instances, SageMaker training, and deployed inference containers are internet accessible or enabled by default. The sagemaker:VpcSubnets condition key can be used to restrict launching these resources in a VPC. For more information, see Condition keys for Amazon SageMaker, Connect to Resources From Within a VPC, and Run Training and Inference Containers in Internet-Free Mode.

Detective controls

The AWS Well-Architected Framework recommends applying a defense in-depth approach with multiple security controls (see Security Pillar). This is why in addition to the preventative controls discussed in the form of condition keys in this post, you should also consider using AWS native fully managed governance tools to help you manage your environment’s deployed resources and their conformance to your data perimeter (see Management and Governance on AWS).

For example, AWS Config provides managed rules to check for Lambda functions inside a VPC and Sagemaker notebooks inside a VPC. You can also use the built-in checks of AWS Security Hub to detect and consolidate findings, such as [Lambda.3] Lambda functions should be in a VPC and [SageMaker.2] SageMaker notebook instances should be launched in a custom VPC.

You can also use similar detective controls for AWS services that don’t currently offer built-in preventative controls. For example, OpenSearch Service has an AWS Config managed rule for OpenSearch in VPC only and security hub check for [Opensearch.2] OpenSearch domains should be in a VPC.

Conclusion

In this post, we discussed how you can enforce that specific AWS services resources can only be created such that they adhere to your data perimeter. We used a sample scenario to dive into AWS Lambda and its network deployment options. We then used IAM condition keys as preventative controls to enforce predictable creation of Lambda functions conforming with our security standard. We also discussed additional AWS services that have similar behavior when the same concepts apply. Finally, we briefly discussed some AWS provided managed rules and security checks that you can use as supplementary detective controls to ensure that your preventative controls are in effect as expected.

Additional resources

The following are some additional resources that you can use to further explore data perimeters.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Harsha Sharma

Harsha Sharma

Harsha is a Principal Solutions Architect with AWS in New York. He joined AWS in 2016 and works with Global Financial Services customers to design and develop architectures on AWS, supporting their journey on the AWS Cloud.

Visualize Amazon DynamoDB insights in Amazon QuickSight using the Amazon Athena DynamoDB connector and AWS Glue

Post Syndicated from Antonio Samaniego Jurado original https://aws.amazon.com/blogs/big-data/visualize-amazon-dynamodb-insights-in-amazon-quicksight-using-the-amazon-athena-dynamodb-connector-and-aws-glue/

Amazon DynamoDB is a fully managed, serverless, key-value NoSQL database designed to run high-performance applications at any scale. DynamoDB offers built-in security, continuous backups, automated multi-Region replication, in-memory caching, and data import and export tools. The scalability and flexible data schema of DynamoDB make it well-suited for a variety of use cases. These include internet-scale web and mobile applications, low-latency metadata stores, high-traffic retail websites, Internet of Things (IoT) and time series data, online gaming, and more.

Data stored in DynamoDB is the basis for valuable business intelligence (BI) insights. To make this data accessible to data analysts and other consumers, you can use Amazon Athena. Athena is a serverless, interactive service that allows you to query data from a variety of sources in heterogeneous formats, with no provisioning effort. Athena accesses data stored in DynamoDB via the open source Amazon Athena DynamoDB connector. Table metadata, such as column names and data types, is stored using the AWS Glue Data Catalog.

Finally, to visualize BI insights, you can use Amazon QuickSight, a cloud-powered business analytics service. QuickSight makes it straightforward for organizations to build visualizations, perform ad hoc analysis, and quickly get business insights from their data, anytime, on any device. Its generative BI capabilities enable you to ask questions about your data using natural language, without having to write SQL queries or learn a BI tool.

This post shows how you can use the Athena DynamoDB connector to easily query data in DynamoDB with SQL and visualize insights in QuickSight.

Solution overview

The following diagram illustrates the solution architecture.

Architecture Diagram

  1. The Athena DynamoDB connector runs in a pre-built, serverless AWS Lambda function. You don’t need to write any code.
  2. AWS Glue provides supplemental metadata from the DynamoDB table. In particular, an AWS Glue crawler is run to infer and store the DynamoDB table format, schema, and associated properties in the Glue Data Catalog.
  3. The Athena editor is used to test the connector and perform analysis via SQL queries.
  4. QuickSight uses the Athena connector to visualize BI insights from DynamoDB.

This walkthrough uses data from the ProductCatalog table, part of the DynamoDB developer guide sample data files.

Prerequisites

Before you get started, you should meet the following prerequisites:

Set up the Athena DynamoDB connector

The Athena DynamoDB connector comprises a pre-built, serverless Lambda function provided by AWS that communicates with DynamoDB so you can query your tables with SQL using Athena. The connector is available in the AWS Serverless Application Repository, and is used to create the Athena data source for later use in data analysis and visualization. To set up the connector, complete the following steps:

  1. On the Athena console, choose Data sources in the navigation pane.
  2. Choose Create data source.
  3. In the search bar, search for and choose Amazon DynamoDB.
  4. Choose Next.
  5. Under Data source details, enter a name. Note that this name should be unique and will be referenced in your SQL statements when you query your Athena data source.
  6. Under Connection details, choose Create Lambda function.

This will take you to the Lambda applications page on the Lambda console. Do not close the Athena data source creation tab; you will return to it in a later step.

  1. Scroll down to Application settings and enter a value for the following parameters (leave the other parameters as default):
    • SpillBucket – Specifies the Amazon Simple Storage Service (Amazon S3) bucket name for storing data that exceeds Lambda function response size limits. To create an S3 bucket, refer to Creating a bucket.
    • AthenaCatalogName – A lowercase name for the Lambda function to be created.Lambda Application Settings
  2. Select the acknowledgement check box and choose Deploy.

Wait for deployment to complete before moving to the next step.

  1. Return to the Athena data source creation tab.
  2. Under Connection details, choose the refresh icon and choose the Lambda function you created.Lambda Connection Details
  3. Choose Next.
  4. Review and choose Create data source.

Provide supplemental metadata via AWS Glue

The Athena connector already comes with a built-in inference capability to discover the schema and table properties of your data source. However, this capability is limited. To accurately discover the metadata of your DynamoDB table and centralize schema management as your data evolves over time, the connector integrates with AWS Glue.

To achieve this, an AWS Glue crawler is run to automatically determine the format, schema, and associated properties of the raw data stored in your DynamoDB table, writing the resulting metadata to a Glue database. Glue databases contain tables, which hold metadata from different data stores, independent from the actual location of the data. The Athena connector then references the Glue table and retrieves the corresponding DynamoDB metadata to enable queries.

Create the AWS Glue database

Complete the following steps to create the Glue database:

  1. On the AWS Glue console, under Data Catalog in the navigation pane, choose Databases.
  2. Choose Add database (you can also edit an existing database if you already have one).
  3. For Name, enter a database name.
  4. For Location, enter the string literal dynamo-db-flag. This keyword indicates that the database contains tables that the connector can use for supplemental metadata.
  5. Choose Create database.

Following security best practices, it is also recommended that you enable encryption at rest for your Data Catalog. For details, refer to Encrypting your Data Catalog.

Create the AWS Glue crawler

Complete the following steps to create and run the Glue crawler:

  1. On the AWS Glue console, under Data Catalog in the navigation pane, choose Crawlers.
  2. Choose Create crawler.
  3. Enter a crawler name and choose Next.
  4. For Data sources, choose Add a data source.
  5. On the Data source drop-down menu, choose DynamoDB. For Table name, enter the name of your DynamoDB table (string literal).
  6. Choose Add a DynamoDB data source.
  7. Choose Next.
  8. For IAM Role, choose Create new IAM role.
  9. Enter a role name and choose Create. This will automatically create an IAM role that trusts AWS Glue and has permissions to access the crawler targets.
  10. Choose Next.
  11. For Target database, choose the database previously created.
  12. Choose Next.
  13. Review and choose Create crawler.
  14. On the newly created crawler page, choose Run crawler.

Crawler runtimes depend on your DynamoDB table size and properties. You can find crawler run details under Crawler runs.

Validate the output metadata

When your crawler run status shows as Completed, follow the below steps to validate the output metadata:

  1. On the AWS Glue console, choose Tables in the navigation pane. Here, you can confirm a new table has been added to the database as a result of the crawler run.
  2. Navigate to the newly created table and take a look at the Schema tab. This tab shows the column names, data types, and other parameters inferred from your DynamoDB table.
  3. If needed, edit the schema by choosing Edit schema.Glue Table Details
  4. Choose Advanced properties.
  5. Under Table properties, verify the crawler automatically created and set the classification key to dynamodb. This indicates to the Athena connector that the table can be used for supplemental metadata.
  6. Optionally, add the following properties to correctly catalog and reference DynamoDB data in AWS Glue and Athena queries. This is due to capital letters not being permitted in AWS Glue table and column names, but being permitted in DynamoDB table and attribute names.
    1. If your DynamoDB table name contains any capital letters, choose Actions and Edit Table and add an extra table property as follows:
      • Key: sourceTable
      • Value: YourDynamoDBTableName
    2. If your DynamoDB table has attributes that contain any capital letters, add an extra table property as follows:
      • Key: columnMapping
      • Value: yourcolumn1=YourColumn1, yourcolumn2=YourColumn2, …

Test the connector with the Athena SQL editor

After the Athena DynamoDB connector is deployed and the AWS Glue table is populated with supplemental metadata, the DynamoDB table is ready for analysis. The example in this post uses the Athena editor to make SQL queries to the ProductCatalog table. For further options to interact with Athena, see Accessing Athena.

Complete the following steps to test the connector:

  1. Open the Athena query editor.
  2. If this is your first time visiting the Athena console in your current AWS Region, complete the following steps. This is a prerequisite before you can run Athena queries. See Getting Started for more details.
    1. Choose Query editor in the navigation pane to open the editor.
    2. Navigate to Settings and choose Manage to set up a query result location in Amazon S3.
  3. Under Data, select the data source and database you created (you may need to choose the refresh icon for them to sync up with Athena).
  4. Tables belonging to the selected database appear under Tables. You can choose a table name for Athena to show the table column list and data types.
  5. Test the connector by pulling data from your table via a SELECT statement. When you run Athena queries, you can reference Athena data sources, databases, and tables as <datasource_name>.<database>.<table_name>. Retrieved records are shown under Results.

For increased security, refer to Encrypting Athena query results stored in Amazon S3 to encrypt query results at rest.

Athena Query Results

For this post, we run a SELECT statement to validate the process. You can refer to the SQL reference for Athena to build more complex queries and analyses.

Visualize in QuickSight

QuickSight allows for building modern interactive dashboards, paginated reports, embedded analytics, and natural language queries through a unified BI solution. In this step, we use QuickSight to generate visual insights from the DynamoDB table by connecting to the Athena data source previously created.

Allow QuickSight to access to resources

Complete the following steps to grant QuickSight access to resources:

  1. On the QuickSight console, choose the profile icon and choose Manage QuickSight.
  2. In the navigation pane, choose Security & Permissions.
  3. Under QuickSight access to AWS services, choose Manage.
  4. QuickSight may ask you to switch to the Region in which users and groups in your account are managed. To change the current Region, navigate to the profile icon on the QuickSight console and choose the Region you want to switch to.
  5. For IAM Role, choose Use QuickSight-managed role (default).

Subsequent instructions assume that the default QuickSight-managed role is being used. If this is not the case, make sure to update the existing role to the same effect.

  1. Under Allow access and autodiscovery for these resources, select IAM and Amazon S3.
  2. For Amazon S3, choose Select S3 buckets.
  3. Choose the spill bucket you specified in earlier when deploying the Lambda function for the connector and the bucket you specified as the Athena query result location in Amazon S3.
  4. For both buckets, select Write permission for Athena Workgroup.
  5. Choose Amazon Athena.
  6. In the pop-up window, choose Next.
  7. Choose Lambda and choose the Amazon Resource Name (ARN) of the Lambda function previously used for the Athena data source connector.
  8. Choose Finish.
  9. Choose Save.

Create the Athena dataset

To create the Athena dataset, complete the following steps:

  1. On the QuickSight console, choose the user profile and switch to the Region you deployed the Athena data source to.
  2. Return to the QuickSight home page.
  3. In the navigation pane, choose Datasets.
  4. Choose New dataset.
  5. For Create a Dataset, select Athena.
  6. For Data source name, enter a name and choose Validate connection.
  7. When the connection shows as Validated, choose Create data source.
  8. Under Catalog, Database, and Tables, select the Athena data source, AWS Glue database, and AWS Glue table previously created.
  9. Choose Select.
  10. On the Finish dataset creation page, select Import to SPICE for quicker analytics.
  11. Choose Visualize.

For additional information on QuickSight query modes, see Importing data into SPICE and Using SQL to customize data.

Build QuickSight visualizations

Once the DynamoDB data is available in QuickSight via the Athena DynamoDB connector, it is ready to be visualized. The QuickSight analysis in the below example shows a vertical stacked bar chart with the average price per product category for the ProductCatalog sample dataset. In addition, it shows a donut chart with the proportion of products by product category, and a tree map containing the count of bicycles per bicycle type.

If you use data imported to SPICE in a QuickSight analysis, the dataset will only be available after the import is complete. For further details, see Using SPICE data in an analysis.

Quicksight Analysis

For comprehensive information on how to create and share visualizations in QuickSight, refer to Visualizing data in Amazon QuickSight and Sharing and subscribing to data in Amazon QuickSight.

Clean up

To avoid incurring continued AWS usage charges, make sure you delete all resources created as part of this walkthrough.

  • Delete the Athena data source:
    1. On the Athena console, switch to the Region you deployed your resources in.
    2. Choose Data sources in the navigation pane.
    3. Select the data source you created and on the Actions menu, choose Delete.
  • Delete the Lambda application:
    1. On the AWS CloudFormation console, switch to the Region you deployed your resources in.
    2. Choose Stacks in the navigation pane.
    3. Select serverlessrepo-AthenaDynamoDBConnector and choose Delete.
  • Delete the AWS Glue resources:
    1. On the AWS Glue console, switch to the Region you deployed your resources in.
    2. Choose Databases in the navigation pane.
    3. Select the database you created and choose Delete.
    4. Choose Crawlers in the navigation pane.
    5. Select the crawler you created and on the Action menu, choose Delete crawler.
  • Delete the QuickSight resources:
    1. On the QuickSight console, switch to the Region you deployed your resources in.
    2. Delete the analysis created for this walkthrough.
    3. Delete the Athena dataset created for this walkthrough.
    4. If you no longer need the Athena data source to create other datasets, delete the data source.

Summary

This post demonstrated how you can use the Athena DynamoDB connector to query data in DynamoDB with SQL and build visualizations in QuickSight.

Learn more about the Athena DynamoDB connector in the Amazon Athena User Guide. Discover more available data source connectors to query and visualize a variety of data sources without setting up or managing any infrastructure while only paying for the queries you run.

For advanced QuickSight capabilities powered by AI, see Gaining insights with machine learning (ML) in Amazon QuickSight and Answering business questions with Amazon QuickSight Q.


About the Authors

Antonio Samaniego Jurado is a Solutions Architect at Amazon Web Services. With a strong passion for modern technology, Antonio helps customers build state-of-the-art applications on AWS. A creator at heart, he loves community-driven learning and sharing of best practices across the AWS service portfolio to make the best of customers cloud journey.

Pascal Vogel is a Solutions Architect at Amazon Web Services. Pascal helps startups and enterprises build cloud-native solutions. As a cloud enthusiast, Pascal loves learning new technologies and connecting with like-minded customers who want to make a difference in their cloud journey.

Implement data warehousing solution using dbt on Amazon Redshift

Post Syndicated from Seshadri Senthamaraikannan original https://aws.amazon.com/blogs/big-data/implement-data-warehousing-solution-using-dbt-on-amazon-redshift/

Amazon Redshift is a cloud data warehousing service that provides high-performance analytical processing based on a massively parallel processing (MPP) architecture. Building and maintaining data pipelines is a common challenge for all enterprises. Managing the SQL files, integrating cross-team work, incorporating all software engineering principles, and importing external utilities can be a time-consuming task that requires complex design and lots of preparation.

dbt (DataBuildTool) offers this mechanism by introducing a well-structured framework for data analysis, transformation and orchestration. It also applies general software engineering principles like integrating with git repositories, setting up DRYer code, adding functional test cases, and including external libraries. This mechanism allows developers to focus on preparing the SQL files per the business logic, and the rest is taken care of by dbt.

In this post, we look into an optimal and cost-effective way of incorporating dbt within Amazon Redshift. We use Amazon Elastic Container Registry (Amazon ECR) to store our dbt Docker images and AWS Fargate as an Amazon Elastic Container Service (Amazon ECS) task to run the job.

How does the dbt framework work with Amazon Redshift?

dbt has an Amazon Redshift adapter module named dbt-redshift that enables it to connect and work with Amazon Redshift. All the connection profiles are configured within the dbt profiles.yml file. In an optimal environment, we store the credentials in AWS Secrets Manager and retrieve them.

The following code shows the contents of profile.yml:

SampleProject:

target: dev
outputs:
dev:
type: redshift
host: "{{ env_var('DBT_HOST') }}"
user: "{{ env_var('DBT_USER') }}"
password: "{{ env_var('DBT_PASSWORD') }}"
port: 5439
dbname: "{{ env_var('DBT_DB_NAME') }}"
schema: dev
threads: 4
keepalives_idle: 240 # default 240 seconds
connect_timeout: 10 # default 10 seconds
sslmode: require
ra3_node: true

The following diagram illustrates the key components of the dbt framework:

The primary components are as follows:

  • Models – These are written as a SELECT statement and saved as a .sql file. All the transformation queries can be written here which can be materialized as a table or view. The table refresh can be full or incremental based on the configuration. For more information, refer SQL models.
  • Snapshots – These implements type-2 slowly changing dimensions (SCDs) over mutable source tables. These SCDs identify how a row in a table changes over time.
  • Seeds – These are CSV files in your dbt project (typically in your seeds directory), which dbt can load into your data warehouse using the dbt seed command.
  • Tests – These are assertions you make about your models and other resources in your dbt project (such as sources, seeds, and snapshots). When you run dbt test, dbt will tell you if each test in your project passes or fails.
  • Macros – These are pieces of code that can be reused multiple times. They are analogous to “functions” in other programming languages, and are extremely useful if you find yourself repeating code across multiple models.

These components are stored as .sql files and are run by dbt CLI commands. During the run, dbt creates a Directed Acyclic Graph (DAG) based on the internal reference between the dbt components. It uses the DAG to orchestrate the run sequence accordingly.

Multiple profiles can be created within the profiles.yml file, which dbt can use to target different Redshift environments while running. For more information, refer to Redshift set up.

Solution overview

The following diagram illustrates our solution architecture.

The workflow contains the following steps:

  1. The open source dbt-redshift connector is used to create our dbt project including all the necessary models, snapshots, tests, macros and profiles.
  2. A Docker image is created and pushed to the ECR repository.
  3. The Docker image is run by Fargate as an ECS task triggered via AWS Step Functions. All the Amazon Redshift credentials are stored in Secrets Manager, which is then used by the ECS task to connect with Amazon Redshift.
  4. During the run, dbt converts all the models, snapshots, tests and macros to Amazon Redshift compliant SQL statements and it orchestrates the run based on the internal data lineage graph maintained. These SQL commands are run directly on the Redshift cluster and therefore the workload is pushed to Amazon Redshift directly.
  5. When the run is complete, dbt will create a set of HTML and JSON files to host the dbt documentation, which describes the data catalog, compiled SQL statements, data lineage graph, and more.

Prerequisites

You should have the following prerequisites:

  • A good understanding of the dbt principles and implementation steps.
  • An AWS account with user role permission to access the AWS services used in this solution.
  • Security groups for Fargate to access the Redshift cluster and Secrets Manager from Amazon ECS.
  • A Redshift cluster. For creation instructions, refer to Create a cluster.
  • An ECR repository: For instructions, refer to Creating a private repository
  • A Secrets Manager secret containing all the credentials for connecting to Amazon Redshift. This includes the host, port, database name, user name, and password. For more information, refer to Create an AWS Secrets Manager database secret.
  • An Amazon Simple Storage (Amazon S3) bucket to host documentation files.

Create a dbt project

We are using dbt CLI so all commands are run in the command line. Therefore, install pip if not already installed. Refer to installation for more information.

To create a dbt project, complete the following steps:

  1. Install dependent dbt packages:
    pip install dbt-redshift
  2. Initialize a dbt project using the dbt init <project_name> command, which creates all the template folders automatically.
  3. Add all the required DBT artifacts.
    Refer to the dbt-redshift-etlpattern repo which includes a reference dbt project. For more information about building projects, refer to About dbt projects.

In the reference project, we have implemented the following features:

  • SCD type 1 using incremental models
  • SCD type 2 using snapshots
  • Seed look-up files
  • Macros for adding reusable code in the project
  • Tests for analyzing inbound data

The Python script is prepared to fetch the credentials required from Secrets Manager for accessing Amazon Redshift. Refer to the export_redshift_connection.py file.

  1. Prepare the run_dbt.sh script to run the dbt pipeline sequentially. This script is placed in the root folder of the dbt project as shown in sample repo.
-- Import the dependent external libraries
dbt deps --profiles-dir . --project-dir .

-- Create tables based on the seed files
dbt seed --profiles-dir . --project-dir .

-- Run all the model files
dbt run --profiles-dir . --project-dir .

-- Run all the snapshot files
dbt snapshot --profiles-dir . --project-dir .

-- Run all inbuilt and custom test cases prepared
dbt test --profiles-dir . --project-dir .

-- Generate dbt documentation files
dbt docs generate --profiles-dir . --project-dir .

--Copying dbt outputs to s3 bucket - for hosting
aws s3 cp --recursive --exclude="*" --include="*.json" --include="*.html" dbt/target/ s3://<bucketName>/REDSHIFT_POC/
  1. Create a Docker file in the parent directory of the dbt project folder. This step builds the image of the dbt project to be pushed to the ECR repository.
FROM python:3

ADD dbt_src /dbt_src

RUN pip install -U pip

# Install DBT libraries
RUN pip install --no-cache-dir dbt-core

RUN pip install --no-cache-dir dbt-redshift

RUN pip install --no-cache-dir boto3

RUN pip install --no-cache-dir awscli

WORKDIR /dbt_src

RUN chmod -R 755 .

ENTRYPOINT [ "/bin/sh", "-c" ]

CMD ["./run_dbt.sh"]

Upload the image to Amazon ECR and run it as an ECS task

To push the image to the ECR repository, complete the following steps:

  1. Retrieve an authentication token and authenticate your Docker client to your registry:
    aws ecr get-login-password --region <region_name> | docker login --username AWS --password-stdin <repository_name>

  2. Build your Docker image using the following command:
docker build -t <image tag> .
  1. After the build is complete, tag your image so you can push it to the repository:
docker tag <image tag>:latest <repository_name>:latest
  1. Run the following command to push the image to your newly created AWS repository:
docker push <repository_name>/<image tag>:latest
  1. On the Amazon ECS console, create a cluster with Fargate as an infrastructure option.
  2. Provide your VPC and subnets as required.
  3. After you create the cluster, create an ECS task and assign the created dbt image as the task definition family.
  4. In the networking section, choose your VPC, subnets, and security group to connect with Amazon Redshift, Amazon S3 and Secrets Manager.

This task will trigger the run_dbt.sh pipeline script and run all the dbt commands sequentially. When the script is complete, we can see the results in Amazon Redshift and the documentation files pushed to Amazon S3.

  1. You can host the documentation via Amazon S3 static website hosting. For more information, refer to Hosting a static website using Amazon S3.
  2. Finally, you can run this task in Step Functions as an ECS task to schedule the jobs as required. For more information, refer to Manage Amazon ECS or Fargate Tasks with Step Functions.

The dbt-redshift-etlpattern repo now has all the code samples required.

Cost for executing dbt jobs in AWS Fargate as an Amazon ECS task with minimal operational requirements would take around $1.5 (cost_link) per month.

Clean up

Complete the following steps to clean up your resources:

  1. Delete the ECS Cluster you created.
  2. Delete the ECR repository you created for storing the image files.
  3. Delete the Redshift Cluster you created.
  4. Delete the Redshift Secrets stored in Secrets Manager.

Conclusion

This post covered the basic implementation of using dbt with Amazon Redshift in a cost-efficient way by using Fargate in Amazon ECS. We described the key infrastructure and configuration set-up with a sample project. This architecture can help you take advantage of the benefits of having a dbt framework to manage your data warehouse platform in Amazon Redshift.

For more information about dbt macros and models for Amazon Redshift internal operation and maintenance, refer to the following GitHub repo. In subsequent post, we’ll explore the traditional extract, transform, and load (ETL) patterns that you can implement using the dbt framework in Amazon Redshift. Test this solution in your account and provide feedback or suggestions in the comments.


About the Authors

Seshadri Senthamaraikannan is a data architect with AWS professional services team based in London, UK. He is well experienced and specialised in Data Analytics and works with customers focusing on building innovative and scalable solutions in AWS Cloud to meet their business goals. In his spare time, he enjoys spending time with his family and play sports.
Mohamed Hamdy is a Senior Big Data Architect with AWS Professional Services based in London, UK. He has over 15 years of experience architecting, leading, and building data warehouses and big data platforms. He helps customers develop big data and analytics solutions to accelerate their business outcomes through their cloud adoption journey. Outside of work, Mohamed likes travelling, running, swimming and playing squash.

The attendee’s guide to the AWS re:Invent 2023 Compute track

Post Syndicated from Chris Munns original https://aws.amazon.com/blogs/compute/the-attendees-guide-to-the-aws-reinvent-2023-compute-track/

This post by Art Baudo – Principal Product Marketing Manager – AWS EC2, and Pranaya Anshu – Product Marketing Manager – AWS EC2

We are just a few weeks away from AWS re:Invent 2023, AWS’s biggest cloud computing event of the year. This event will be a great opportunity for you to meet other cloud enthusiasts, find productive solutions that can transform your company, and learn new skills through 2000+ learning sessions.

Even if you are not able to join in person, you can catch-up with many of the sessions on-demand and even watch the keynote and innovation sessions live.

If you’re able to join us, just a reminder we offer several types of sessions which can help maximize your learning in a variety of AWS topics. Breakout sessions are lecture-style 60-minute informative sessions presented by AWS experts, customers, or partners. These sessions are recorded and uploaded a few days after to the AWS Events YouTube channel.

re:Invent attendees can also choose to attend chalk-talks, builder sessions, workshops, or code talk sessions. Each of these are live non-recorded interactive sessions.

  • Chalk-talk sessions: Attendees will interact with presenters, asking questions and using a whiteboard in session.
  • Builder Sessions: Attendees participate in a one-hour session and build something.
  • Workshops sessions: Attendees join a two-hour interactive session where they work in a small team to solve a real problem using AWS services.
  • Code talk sessions: Attendees participate in engaging code-focused sessions where an expert leads a live coding session.

To start planning your re:Invent week, check-out some of the Compute track sessions below. If you find a session you’re interested in, be sure to reserve your seat for it through the AWS attendee portal.

Explore the latest compute innovations

This year AWS compute services have launched numerous innovations: From the launch of over 100 new Amazon EC2 instances, to the general availability of Amazon EC2 Trn1n instances powered by AWS Trainium and Amazon EC2 Inf2 instances powered by AWS Inferentia2, to a new way to reserve GPU capacity with Amazon EC2 Capacity Blocks for ML. There’s a lot of exciting launches to take in.

Explore some of these latest and greatest innovations in the following sessions:

  • CMP102 | What’s new with Amazon EC2
    Provides an overview on the latest Amazon EC2 innovations. Hear about recent Amazon EC2 launches, learn how about differences between Amazon EC2 instances families, and how you can use a mix of instances to deliver on your cost, performance, and sustainability goals.
  • CMP217 | Select and launch the right instance for your workload and budget
    Learn how to select the right instance for your workload and budget. This session will focus on innovations including Amazon EC2 Flex instances and the new generation of Intel, AMD, and AWS Graviton instances.
  • CMP219-INT | Compute innovation for any application, anywhere
    Provides you with an understanding of the breadth and depth of AWS compute offerings and innovation. Discover how you can run any application, including enterprise applications, HPC, generative artificial intelligence (AI), containers, databases, and games, on AWS.

Customer experiences and applications with machine learning

Machine learning (ML) has been evolving for decades and has an inflection point with generative AI applications capturing widespread attention and imagination. More customers, across a diverse set of industries, choose AWS compared to any other major cloud provider to build, train, and deploy their ML applications. Learn about the generative AI infrastructure at Amazon or get hands-on experience building ML applications through our ML focused sessions, such as the following:

Discover what powers AWS compute

AWS has invested years designing custom silicon optimized for the cloud to deliver the best price performance for a wide range of applications and workloads using AWS services. Learn more about the AWS Nitro System, processors at AWS, and ML chips.

Optimize your compute costs

At AWS, we focus on delivering the best possible cost structure for our customers. Frugality is one of our founding leadership principles. Cost effective design continues to shape everything we do, from how we develop products to how we run our operations. Come learn of new ways to optimize your compute costs through AWS services, tools, and optimization strategies in the following sessions:

Check out workload-specific sessions

Amazon EC2 offers the broadest and deepest compute platform to help you best match the needs of your workload. More SAP, high performance computing (HPC), ML, and Windows workloads run on AWS than any other cloud. Join sessions focused around your specific workload to learn about how you can leverage AWS solutions to accelerate your innovations.

Hear from AWS customers

AWS serves millions of customers of all sizes across thousands of use cases, every industry, and around the world. Hear customers dive into how AWS compute solutions have helped them transform their businesses.

Ready to unlock new possibilities?

The AWS Compute team looks forward to seeing you in Las Vegas. Come meet us at the Compute Booth in the Expo. And if you’re looking for more session recommendations, check-out additional re:Invent attendee guides curated by experts.

Simplify your SMS setup with the new Amazon Pinpoint SMS console

Post Syndicated from hamzarau original https://aws.amazon.com/blogs/messaging-and-targeting/send-sms-using-the-new-amazon-pinpoint-sms-console/

Amazon Pinpoint is a multichannel communication service that helps application developers engage their customers through communication channels such as SMS or text messaging, email, mobile push, voice, and in-app messaging.

Amazon Pinpoint SMS provides the global scale, resiliency, and flexibility required to deliver SMS and voice messaging in web, mobile, or business applications. SMS messaging is used for use cases like one-time passcode validation, time sensitive alerts, and two-way chat due to its global reach and ubiquity. Today Amazon Pinpoint SMS sends messages to over 240 countries and regions. In this post, we will review how to use the new Pinpoint SMS management console to get your SMS resources setup correctly the first time.

This blog walks through the setup and configuration steps for Pinpoint SMS using the management console. Additionally, all setup and configurations can also be completed using Pinpoint SMS APIs. For more information visit the Pinpoint SMS documentation, or complete the Amazon Pinpoint SMS workshop.

The Pinpoint SMS management console provides control for the existing functionality of the Pinpoint SMS APIs to create, and manage your SMS and voice resources. In addition, the Pinpoint SMS console has a Quick start – SMS setup guide or Request originator flow to guide you through the setup process and for requesting and managing your SMS resources.

If you require additional background on how SMS works using Amazon Pinpoint SMS, refer to How to Manage Global Sending of SMS with Amazon Pinpoint. Below are some important SMS concepts we’ll highlight in this blog post.

Important SMS Concepts and Resources

  • Phone pool: The phone pool resource is a collection of phone numbers and sender IDs that all share the same settings and provide failover if a number becomes unavailable.
  • Originator: An originator refers to either a phone number or sender ID.
  • Phone number: Also called originator number, a phone number is a numeric string of numbers that identifies the sender. This can be a long code, short code, toll-free number (TFN), or 10-digit long code (10DLC). For more information see choosing a phone number or sender ID.
  • Verified destination phone number: When your account is in Sandbox you can only send SMS messages to phone numbers that have gone through the verification process. The phone number receives an SMS message with a verification code. The received code must be entered into the console to complete the process.
  • Simulator phone number: A simulator phone number behaves as any other origination and destination phone number without sending the SMS message to mobile carriers. Simulator phone numbers do not require registration and are used for testing scenarios.
  • Sender ID: Also called originator ID, a sender ID is an alphanumeric string that identifies the sender. For more information see choosing a phone number or sender ID.
  • Registered phone number: Some countries require you to register your company’s identity before you can purchase phone numbers or sender IDs. They also require a review of the messages that you send to recipients in their country. Registrations are processed by external third parties, so the amount of time to process a registration varies by phone number type and country. After all required registrations are complete, the status of your phone numbers changes to Active and is available for use. For more information about which countries require registration see, supported countries and regions (SMS channel).

Getting started

Sign-in to the AWS management console and search for Amazon Pinpoint. If you don’t have an existing AWS account, complete the following steps to create one.

In the Amazon Pinpoint console, you can choose between managing Pinpoint SMS and Pinpoint campaign orchestration. Pinpoint SMS is the place where applications developers go to setup and configure their associated resources for SMS sending through any AWS service. Pinpoint campaign orchestration is for builders who want to manage their customer segments and send messages using campaigns, or multi-step journeys. Campaign orchestration utilizes communication channels like Pinpoint SMS or Amazon SES (simple email service) to deliver its messages. In this blog, we will discuss how to configure Pinpoint SMS using its management console.

Amazon Pinpoint SMS Console

Quick start – SMS setup guide

Once you’ve selected the Amazon Pinpoint SMS console, you will land on the Overview page. On this page, you get a summary of your SMS resources and the Quick start – SMS setup guide. This guide will walk you through creating the appropriate SMS resources to start sending SMS messages. The steps outlined in the Quick start guide are recommended but not required.

Step 1: Create a phone pool

A phone pool is a collection of phone numbers and sender IDs that all share the same settings and provide failover if a number becomes unavailable. Phone pools provide the benefit of managing for number resiliency, removes the complexity from sending applications, and provides a logical grouping to manage phone numbers and sender IDs. For example, phone pools can be grouped by use-case such as having a phone pool for OTP (one-time password) messages.

In the navigation pane, under Overview, in the Quick start section, choose Create pool. Under the pool setup section, enter a name for your pool in Pool name. To create a pool, you will need to select an origination identity, either a phone number or sender ID to associate with the pool. Additional origination identities can be added once the pool is created on the Phone pools page. If you don’t have an active phone number or sender ID in your account, we recommend selecting a simulator number, which can be used for testing and does not require any registration. Once you’ve selected an origination identity, you can choose Create phone pool to complete step 1.

Setting up phone pools for sending SMS

Step 2: Create a configuration set

A configuration set is a set of rules that are applied when you send a message. For example, a configuration set can specify a destination for events related to a message. When SMS events occur (such as delivery or failure events), they are routed to the destination associated with the configuration set that you specified when you sent the message. You’re not required to use configuration sets when you send messages, but we recommend that you do. We support sending SMS and voice events to Amazon CloudWatch, Amazon Kinesis DataFirehose, and Amazon SNS.

In the navigation pane, under Overview, in the Quick start section, choose Create set. Under the Configuration set details section, enter a name in Configuration set name. For Event Destination setup, choose either the quick start option to create a Cloud formation stack to automatically create and configure CloudWatch, Kinesis DataFirehose, and SNS to log all events or the advanced option to manually select which event destinations you would like to setup. Once you’ve made the selection, choose Create Configuration set to complete step 2.

How to create a configuration set for sending SMS

Step 3: Test SMS sending

Send a test message using the SMS simulator. Select an originator to send from, and a destination number to send to. To track the status of your message, add a configuration set to publish SMS events.

In the navigation pane, under Overview, in the Quick start section, choose Test SMS sending. Under the Originator section, select either a phone pool, phone number, or sender ID in your account to send test messages from. Next, under the Destination phone number section, select either a simulator number or active destination number to send test messages to. If your account is in Sandbox, you can only send messages to simulator numbers or verified destination numbers. Once your account is in Production you can send messages to simulator numbers or any active destination number. You can (optionally) select a configuration set to track your SMS events. Next, under the Message body section, enter a sample message and send the test message.

Note – If you are sending from a US simulator number (or using a phone pool that only contains a US simulator number) you can only send messages to US simulator destination numbers. A simulator phone number behaves like any other phone number without sending the SMS message to mobile carriers.

SMS simulator in the SMS console

Step 4: Request production Access

Finally, if your account is in Sandbox there are limits to the amount you can spend and can only send to verified destination phone numbers. Request moving your account from Sandbox to Production to remove these limits. To move to Production, open a case with AWS Support Center.

Conclusion

After following the request for Production access, you’ve completed the recommended steps to get your account configuration setup. You have now tested and configured the following resources in your account:

  • Phone pool: A phone pool is a collection of phone numbers and sender IDs that all share the same settings and provide failover if a number becomes unavailable. Phone pools provide the benefit of managing for number resiliency, removes the complexity from sending applications, and provides a logical grouping to manage phone numbers and sender IDs.
    • Originator: As part of the pool setup, you are required to associate at least one originator to the phone pool. An originator refers to either a phone number or sender ID. If you’ve selected a simulator number and would like to now request a new phone number or sender ID, you can do so following Request originator flow.
  • Configuration set: A configuration set allows you to organize, track, and configure logging of your SMS events, specifying where to publish them by adding event destinations.

Next steps

To request additional originators such as phone numbers or sender IDs, you can follow the Request Originator flow in the management console. If your originator requires registrations and is supported, you can self-service the phone number or sender ID registration in the management console.