Tag Archives: AWS Lambda

How to control non-HTTP and non-HTTPS traffic to a DNS domain with AWS Network Firewall and AWS Lambda

Post Syndicated from Tyler Applebaum original https://aws.amazon.com/blogs/security/how-to-control-non-http-and-non-https-traffic-to-a-dns-domain-with-aws-network-firewall-and-aws-lambda/

Security and network administrators can control outbound access from a virtual private cloud (VPC) to specific destinations by using a service like AWS Network Firewall. You can use stateful rule groups to control outbound access to domains for HTTP and HTTPS by default in Network Firewall. In this post, we’ll walk you through how to accomplish this access control for non-HTTP and non-HTTPS traffic, such as SSH (Secure Shell). This solution is extensible to other protocols with static port assignments.

In the example scenario in this post, the network administrator needs to permit outbound SSH access on port 22/tcp to a third-party domain, example.org, from a group of Amazon Elastic Compute Cloud (Amazon EC2) instances that sits inside of a protected VPC that restricts outbound SSH traffic with Network Firewall. Non-HTTP traffic can’t currently be controlled with a domain rule in Network Firewall.

This solution allows administrators to control outbound access to a given domain in a granular way, by resolving the domain name inside of an AWS Lambda function, and updating a Network Firewall rule variable with the results of the DNS query. This solution further restricts specific non-HTTP and non-HTTPS traffic to those allowed domains to only what is explicitly specified by the administrator.

Solution overview

Figure 1 provides an overview of the solution and the resulting traffic flow.
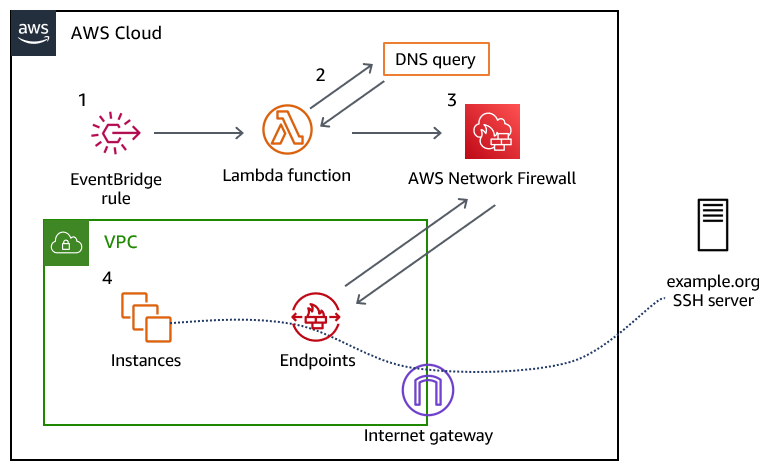
Figure 1: Overview of the solution and the resulting traffic flow

Figure 1: Overview of the solution and the resulting traffic flow

The solution workflow is as follows:

  1. An Amazon EventBridge rule invokes the Lambda function every 10 minutes. You can modify this frequency to meet your needs. You should consider the time-to-live (TTL) record of the DNS record that you are configuring when choosing this interval.
  2. The Lambda function performs the DNS lookup for the provided domain, and updates a variable in an existing Network Firewall rule group. The rule group changes take a few seconds to fully apply to the nodes in your Network Firewall deployment.
  3. The newly created Network Firewall rule group is associated with the Network Firewall policy to control traffic.
  4. Traffic from the instances in your VPC flows through the Network Firewall endpoint, and if allowed, is routed through an internet gateway to the target server.

Prerequisites

This solution has the following prerequisites:

  1. An AWS account. If you don’t have an AWS account, create and activate one.
  2. An existing VPC with default routing to an internet gateway through a network firewall that has a firewall policy attached to it. The example rule included in the solution’s AWS CloudFormation template expects the firewall policy to use the default action order for stateful rule groups. If you don’t have an existing network firewall associated with your VPC, see the AWS Network Firewall Developer Guide to get started. For a walkthrough of the Network Firewall configuration and rules engine, see the blog post Hands-on walkthrough of the AWS Network Firewall flexible rules engine – Part 1.
  3. A DNS domain that you provide, which allows traffic for the protocol and port (or ports) that you plan to allow traffic to. This DNS domain needs to resolve to an IPv4 address or set of addresses; IPv6 is not supported, at this point.

Deploy the solution

We’ve provided a CloudFormation template to deploy this solution, which is located in the GitHub repository that accompanies this blog post.

To deploy the solution

  1. Download the CloudFormation template from our GitHub repository.
  2. Sign in to your AWS account and select the AWS Region where your Network Firewall is deployed.
  3. Navigate to the CloudFormation service.
  4. Choose Stacks > Create Stack > With new resources (standard).
  5. In the Specify template section, choose Upload a template file.
  6. Choose Choose file, navigate to where you saved the CloudFormation template, and upload it. Then choose Next.
  7. Specify a stack name for your CloudFormation stack.
  8. In the Parameters section, for the Domain parameter, specify the name of the domain to which you will control access. The default value is set to example.org; however, note that the actual example.org doesn’t allow SSH traffic.
  9. The remaining parameters have defaults to allow outbound SSH traffic to the specified domain. Adjust the LambdaJobFrequency variable so that it corresponds with the TTL of the DNS record that it will resolve. This allows the Lambda function to keep the IP address of the DNS record up to date, in the event that it changes. After you’ve configured the parameters, choose Next.
    Figure 2: CloudFormation stack parameters

    Figure 2: CloudFormation stack parameters

  10. On the Configure stack options page, specify any further options needed or keep the default options, and then choose Next.
  11. On the Review page, review the stack and parameters and select the check box to acknowledge that this template will create IAM resources. Choose Create Stack.
  12. Check the stack creation status. Upon successful completion, the status shows CREATE_COMPLETE.
    Figure 3: The successful creation of the CloudFormation stack

    Figure 3: The successful creation of the CloudFormation stack

Test the solution

Before you test the newly created rule, make sure that the Lambda function has been invoked at least once from the EventBridge rule.

To verify the Lambda function results

  1. In the AWS Management Console, navigate to the Lambda function Network-Firewall-Resolver-Function, and on the Monitor tab, choose View logs in CloudWatch.
    Figure 4: Navigating to view logs in CloudWatch

    Figure 4: Navigating to view logs in CloudWatch

  2. Select the most recent log stream.
  3. Verify that that a log line contains the entry StatefulRuleGroup updated successfully.
    Figure 5: Examining the CloudWatch logs to verify that the Lambda function ran successfully

    Figure 5: Examining the CloudWatch logs to verify that the Lambda function ran successfully

  4. Associate the stateful rule group that was created by the stack, Lambda-Managed-Stateful-Rule with the existing Network Firewall policy that is attached to your VPC. To do this:
    1. Navigate to VPC > Network Firewall > Firewall Policies and select your existing firewall policy.
    2. In the Stateful rule groups section, for Actions, choose Add unmanaged stateful rule groups.
  5. Select the check box for Lambda-Managed-Stateful-Rule, and then choose Add stateful rule group.
  6. When the newly provisioned Lambda function runs successfully, it will resolve the IPv4 address for the domain (example.org) and associate the address with the stateful rule variable IP_NET. To validate that this has happened, do the following:
    1. Navigate to VPC > Network Firewall > Network Firewall rule groups.
    2. Choose the Lambda-Managed-Stateful-Rule rule group.
    3. Navigate to the rule variable section, and choose IP_NET. If the Lambda function successfully resolved the provided domain name, the variable will contain the IPv4 addresses for the domain you provided, as shown in Figure 6.
      Figure 6: Validating the rule variable details

      Figure 6: Validating the rule variable details

  7. Test the rule by attempting to connect to the domain that you specified in the CloudFormation template. Use an EC2 instance within the VPC that the network firewall rule is associated with, and attempt to establish an SSH connection to the domain that you specified. As shown by the SSH key negotiation in Figure 7, traffic is allowed through the network firewall, as intended.
    Figure 7: SSH connectivity to the domain was successful

    Figure 7: SSH connectivity to the domain was successful

    You can also configure the rule to drop the SSH connection, rather than permit it. To do this:

    1. Navigate to VPC > Network Firewall > Network Firewall rule groups.
    2. Choose the Lambda-Managed-Stateful-Rule rule group. In the Rules section, choose Edit Rules.
    3. Modify the rule to take the Drop action, and save the rule group.

    As shown by the lack of response from the host in Figure 8, the SSH connection cannot be established anymore.

    Figure 8: An SSH connection cannot be established, due to the connection timing out

    Figure 8: An SSH connection cannot be established, due to the connection timing out

Cleanup

Follow the steps in this section to remove the resources created by this solution.

To remove the resources

  1. Sign in to your AWS account where you deployed the CloudFormation stack and navigate to the Network Firewall console.
  2. In the Stateful rule groups section, select the check box for Lambda-Managed-Stateful-Rule. For Actions, choose Disassociate from policy.
    Figure 9: Disassociating the stateful rule from the existing policy

    Figure 9: Disassociating the stateful rule from the existing policy

  3. Navigate to the CloudFormation console, select the stack that you created, and then choose Delete. Upon successful deletion, the resources created by the stack will be deleted.

Conclusion

In this post, we’ve demonstrated how security and network administrators have the ability to permit or restrict non-HTTP and non-HTTPS traffic to a given domain by using Network Firewall. With this solution, administrators can enforce granular port- and protocol-level control to third-party domains. To learn more about rule group configuration in AWS Network Firewall, see Managing your own rule groups in the Developer Guide.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support. You can also start a new thread on AWS Network Firewall re:Post to get answers from the community.

Want more AWS Security news? Follow us on Twitter.

Tyler Applebaum

Tyler Applebaum

Tyler is a Sr. Solutions Architect in the Charlotte, NC area helping customers migrate to AWS and modernize their applications. He has previous experience as a network engineer working in healthcare and finance.

Bhavin Lakhani

Bhavin is a Technical Account Manager in the US West, Northern California, helping customers with their AWS Enterprise Support, Operational, and Architectural needs. He has cloud infrastructure and database platform leadership experience in his previous roles. He loves soccer and is an ardent “Arsenal” fan.

What to consider when modernizing APIs with GraphQL on AWS

Post Syndicated from Lewis Tang original https://aws.amazon.com/blogs/architecture/what-to-consider-when-modernizing-apis-with-graphql-on-aws/

In the next few years, companies will build over 500 million new applications, more than has been developed in the previous 40 years combined (see IDC article). API operations enable innovation. They are the “front door” to applications and microservices, and an integral layer in the application stack. In recent years, GraphQL has emerged as a modern API approach. With GraphQL, companies can improve the performance of their applications and the speed in which development teams can build applications. In this post, we will discuss how GraphQL works and how integrating it with AWS services can help you build modern applications. We will explore the options for running GraphQL on AWS.

How GraphQL works

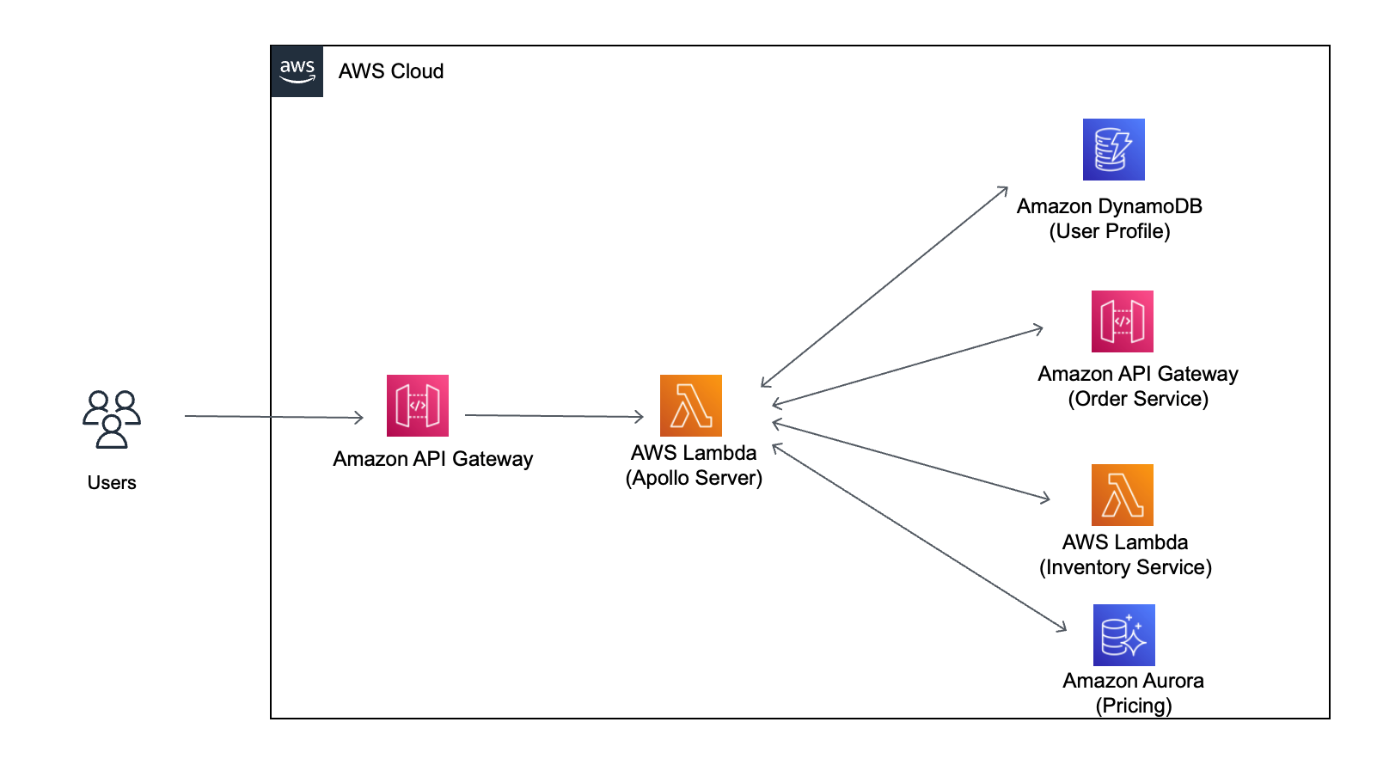
Imagine you have an API frontend implemented with GraphQL for your ecommerce application. As shown in Figure 1, there are different services in your ecommerce system backend that are accessible via different technologies. For example, user profile data is stored in a highly scalable NoSQL table. Orders are accessed through a REST API. The current inventory stock is checked through an AWS Lambda function. And the pricing information is in an SQL database.

How GraphQL works

Figure 1. How GraphQL works

Without using GraphQL, client applications must make multiple separate calls to each one of these services. Because each service is exposed through different API endpoints, the complexity of accessing data from the client side increases significantly. In order to get the data, you have to make multiple calls. In some cases, you might over fetch data as the data source would send you an entire payload including data you might not need. In some other circumstances, you might under fetch data as a single data source would not have all your required data.

A GraphQL API combines the data from all these different services into a single payload that the client defines based on its needs. For example, a smartphone has a smaller screen than a desktop application. A smartphone application might require less data. The data is retrieved from multiple data sources automatically. The client just sees a single constructed payload. This payload might be receiving user profile data from Amazon DynamoDB, or order details from Amazon API Gateway. Or it could involve the injection of specific fields with inventory availability and price data from AWS Lambda and Amazon Aurora.

When modernizing frontend APIs with GraphQL, you can build applications faster because your frontend developers don’t need to wait for backend service teams to create new APIs for integration. GraphQL simplifies data access by interacting with data from multiple data sources using a single API. This reduces the number of API requests and network traffic, which results in improved application performance. Furthermore, GraphQL subscriptions enable two-way communication between the backend and client. It supports publishing updates to data in real time to subscribed clients. You can create engaging applications in real time with use cases such as updating sports scores, bidding statuses, and more.

Options for running GraphQL on AWS

There are two main options for running GraphQL implementation on AWS, fully managed on AWS using AWS AppSync, and self-managed GraphQL.

I. Fully managed using AWS AppSync

The most straightforward way to run GraphQL is by using AWS AppSync, a fully managed service. AWS AppSync handles the heavy lifting of securely connecting to data sources, such as Amazon DynamoDB, and to develop GraphQL APIs. You can write business logic against these data sources by choosing code templates that implement common GraphQL API patterns. Your APIs can also interact with other AWS AppSync functionality such as caching, to improve performance. Use subscriptions to support real-time updates, and client-side data stores to keep offline devices in sync. AWS AppSync will scale automatically to support varied API request loads. You can find more details from the AWS AppSync features page.

AWS AppSync in an ecommerce system implementation

Figure 2. AWS AppSync in an ecommerce system implementation

Let’s take a closer look at this GraphQL implementation with AWS AppSync in an ecommerce system. In Figure 2, a schema is created to define types and capabilities of the desired GraphQL API. You can tie the schema to a Resolver function. The schema can either be created to mirror existing data sources, or AWS AppSync can create tables automatically based the schema definition. You can also use GraphQL features for data discovery without viewing the backend data sources.

After a schema definition is established, an AWS AppSync client can be configured with an operation request, such as a query operation. The client submits the operation request to GraphQL Proxy along with an identity context and credentials. The GraphQL Proxy passes this request to the Resolver, which maps and initiates the request payload against pre-configured AWS data services. These can be an Amazon DynamoDB table for user profile, an AWS Lambda function for inventory service, and more. The Resolver initiates calls to one or all of these services within a single API call. This minimizes CPU cycles and network bandwidth needs. The Resolver then returns the response to the client. Additionally, the client application can change data requirements in code on demand. The AWS AppSync GraphQL API will dynamically map requests for data accordingly, enabling faster prototyping and development.

II. Self-Managed GraphQL

If you want the flexibility of selecting a particular open-source project, you may choose to run your own GraphQL API layer. Apollo, graphql-ruby, Juniper, gqlgen, and Lacinia are some popular GraphQL implementations. You can leverage AWS Lambda or container services such as Amazon Elastic Container Service (ECS) and Amazon Elastic Kubernetes Services (EKS) to run GraphQL open-source implementations. This gives you the ability to fine-tune the operational characteristics of your API.

When running a GraphQL API layer on AWS Lambda, you can take advantage of the serverless benefits of automatic scaling, paying only for what you use, and not having to manage your servers. You can create a private GraphQL API using Amazon ECS, EKS, or AWS Lambda, which can only be accessed from your Amazon Virtual Private Cloud (VPC). With Apollo GraphQL open-source implementation, you can create a Federated GraphQL that allows you to combine GraphQL APIs from multiple microservices into a single API, illustrated in Figure 3. The Apollo GraphQL Federation with AWS AppSync post shows a concrete example of how to integrate an AWS AppSync API with an Apollo Federation gateway. It uses specification-compliant queries and directives.

Apollo GraphQL implementation on AWS Lambda

Figure 3. Apollo GraphQL implementation on AWS Lambda

When choosing self-managed GraphQL implementation, you have to spend time writing non-business logic code to connect data sources. You must implement authorization, authentication, and integrate other common functionalities. This can be caches to improve performance, subscriptions to support real-time updates, and client-side data stores to keep offline devices in sync. Because of these responsibilities, you have less time to focus on the business logic of application.

Similarly, backend development teams and API operators of an open-source GraphQL implementation must provision and maintain their own GraphQL servers. Remember that even with a serverless model, API developers and operators are still responsible for monitoring, performance tuning, and troubleshooting the API platform service.

Conclusion

Modernizing APIs with GraphQL gives your frontend application the ability to fetch just the data that’s needed from multiple data sources with an API call. You can build modern mobile and web applications faster, because GraphQL simplifies API management. You have flexibility to run an open-source GraphQL implementation most closely aligned with your needs on AWS Lambda, Amazon ECS, and Amazon EKS. With AWS AppSync, you can set up GraphQL quickly and increase your development velocity by reducing the amount of non-business API logic code.

Further reading:

How to Automatically Prevent Email Throttling when Reaching Concurrency Limit

Post Syndicated from Mark Richman original https://aws.amazon.com/blogs/messaging-and-targeting/prevent-email-throttling-concurrency-limit/

Introduction

Many users of Amazon Simple Email Service (Amazon SES) send large email campaigns that target tens of thousands of recipients. Regulating the flow of Amazon SES requests can prevent throttling due to exceeding the AWS service limit on the account.

Amazon SES service quotas include a soft limit on the number of emails sent per second (also known as the “sending rate”). This quota is intended to protect users from accidentally sending unintended volumes of email, or from spending more money than intended. Most Amazon SES customers have this quota increased, but very large campaigns may still exceed that limit. As a result, Amazon SES will throttle email requests. When this happens, your messages will fail to reach their destination.

This blog provides users of Amazon SES a mechanism for regulating the flow of messages that are sent to Amazon SES. Cloud Architects, Engineers, and DevOps Engineers designing new, or improving an existing Amazon SES solution would benefit from reading this post.

Overview

A common solution for regulating the flow of API requests to Amazon SES is achieved using Amazon Simple Queue Service (Amazon SQS). Amazon SQS can send, store, and receive messages at virtually any volume and can serve as part of a solution to buffer and throttle the rate of API calls. It achieves this without the need for other services to be available to process the messages. In this solution, Amazon SQS prevents messages from being lost while waiting for them to be sent as emails.

Fig 1 — High level architecture diagram

But this common solution introduces a new challenge. The mechanism used by the Amazon SQS event source mapping for AWS Lambda invokes a function as soon as messages are visible. Our challenge is to regulate the flow of messages, rather than invoke Amazon SES as messages arrive to the queue.

Fig 2 — Leaky bucket

Developers typically limit the flow of messages in a distributed system by implementing the “leaky bucket” algorithm. This algorithm is an analogy to a bucket which has a hole in the bottom from which water leaks out at a constant rate. Water can be added to the bucket intermittently. If too much water is added at once or at too high a rate, the bucket overflows.

In this solution, we prevent this overflow by using throttling. Throttling can be handled in two ways: either before messages reach Amazon SQS, or after messages are removed from the queue (“dequeued”). Both of these methods pose challenges in handling the throttled messages and reprocessing them. These challenges introduce complexity and lead to the excessive use of resources that may cause a snowball effect and make the throttling worse.

Developers often use the following techniques to help improve the successful processing of feeds and submissions:

  • Submit requests at times other than on the hour or on the half hour. For example, submit requests at 11 minutes after the hour or at 41 minutes after the hour. This can have the effect of limiting competition for system resources with other periodic services.
  • Take advantage of times during the day when traffic is likely to be low, such as early evening or early morning hours.

However, these techniques assume that you have control over the rate of requests, which is usually not the case.

Amazon SQS, acting as a highly scalable buffer, allows you to disregard the incoming message rate and store messages at virtually any volume. Therefore, there is no need to throttle messages before adding them to the queue. As long as you eventually process messages faster than you receive new ones, you will be fine with the inflow that will get processed later on.

Regulating flow of messages from Amazon SQS

The proposed solution in this post regulates the dequeue of messages from one or more SQS queues. This approach can help prevent you from exceeding the per-second quota of Amazon SES, thereby preventing Amazon SES from throttling your API calls.

Available configuration controls

When it comes to regulating outflow from Amazon SQS you have a few options. MaxNumberOfMessages controls the maximum number of messages you can dequeue in a single read request. WaitTimeSeconds defines whether Amazon SQS uses short polling (0 seconds wait) or long polling (more than 0 seconds) while waiting to read messages from a queue. Though these capabilities are helpful in many use cases, they don’t provide full control over outflow rates.

Amazon SQS Event source mapping for Lambda is a built-in mechanism that uses a poller within the Lambda service. The poller polls for visible messages in the queue. Once messages are read, they immediately invoke the configured Lambda function. In order to prevent downstream throttling, this solution implements a custom poller to regulate the rate of messages polled instead of the Amazon SQS Event source mechanism.

Custom poller Lambda

Let’s look at the process of implementing a custom poller Lambda function. Your function should actively regulate the outflow rate without throttling or losing any messages.

First, you have to consider how to invoke the poller Lambda function once every second. Using Amazon EventBridge rules you can schedule Lambda invocations at a rate of once per minute. You also have to consider how to complete processing of Amazon SES invocations as soon as possible. And finally, you have to consider how to send requests to Amazon SES at a rate as close as possible to your per-second quota, without exceeding it.

You can use long polling to meet all of these requirements. Using long polling (by setting the WaitTimeSeconds value to a number greater than zero) means the request queries all of the Amazon SQS servers, or waits until the maximum number of messages you can handle per second (the MaxNumberOfMessages value) are read. By setting the MaxNumberOfMessages equal to your Amazon SES request per-second quota, you prevent your requests from exceeding that limit.

By splitting the looping logic from the poll logic (by using two Lambda functions) the code loops every second (60 times per minute) and asynchronously runs the polling logic.

Fig 3 — Custom poller diagram

You can use the following Python code to create the scheduler loop function:

import os
from time import sleep, time_ns

import boto3

SENDER_FUNCTION_NAME = os.getenv("SENDER_FUNCTION_NAME")
lambda_client = boto3.client("lambda")

def lambda_handler(event, context):
    print(event)

    for _ in range(60):
        prev_ns = time_ns()

        response = lambda_client.invoke_async( 
            FunctionName=SENDER_FUNCTION_NAME, InvokeArgs="{}" 
        ) 
        print(response)

        delta_ns = time_ns() - prev_ns

        if delta_ns < 1_000_000_000: 
            secs = (1_000_000_000.0 - delta_ns) / 1_000_000_000 
            sleep(secs)

This Python code creates a poller function:

import json 
import os

import boto3

UNREGULATED_QUEUE_URL = os.getenv("UNREGULATED_QUEUE_URL") 
MAX_NUMBER_OF_MESSAGES = 3 
WAIT_TIME_SECONDS = 1 
CHARSET = "UTF-8"

ses_client = boto3.client("ses") 
sqs_client = boto3.client("sqs")

def lambda_handler(event, context): 
    response = sqs_client.receive_message( 
        QueueUrl=UNREGULATED_QUEUE_URL, 
        MaxNumberOfMessages=MAX_NUMBER_OF_MESSAGES, 
        WaitTimeSeconds=WAIT_TIME_SECONDS, 
    )

    try: 
        messages = response["Messages"] 
    except KeyError: 
        print("No messages in queue") 
        return

    for message in messages: 
        message_body = json.loads(message["Body"]) 
        to_address = message_body["to_address"] 
        from_address = message_body["from_address"] 
        subject = message_body["subject"] 
        body = message_body["body"]

        print(f"Sending email to {to_address}")

        ses_client.send_email( 
            Destination={ 
                "ToAddresses": [ 
                    to_address, 
                ], 
            }, 
            Message={ 
                "Body": { 
                    "Text": { 
                        "Charset": CHARSET, 
                        "Data": body, 
                    } 
                }, 
                "Subject": { 
                    "Charset": CHARSET, 
                    "Data": subject, 
                }, 
            }, 
            Source=from_address, 
        )

        sqs_client.delete_message( 
            QueueUrl=UNREGULATED_QUEUE_URL, ReceiptHandle=message["ReceiptHandle"] 
        )

Regulating flow of prioritized messages from Amazon SQS

In the use case above, you may be serving a very large marketing campaign (“campaign1”) that takes hours to process. At the same time, you may want to process another, much smaller campaign (“campaign2″), which won’t be able to run until campaign1 is complete.

Obvious solution is to prioritize the campaigns by processing both campaigns in parallel. For example, allocate 90% of the Amazon SES per-second capacity limit to process the larger campaign1, while allowing the smaller campaign2 to take 10% of the available capacity under the limit. Amazon SQS does not provide message priority functionalities out-of-the-box. Instead, create two separate queues and poll each queue according to your desired frequency.

Fig 4 — Prioritize campaigns by queue diagram

This solution works fine if you have consistent flow of incoming messages to both queues. Unfortunately, once you finish processing campaign2 you will keep processing campaign1, using only 90% of the limit capacity per second.

Handling unbalanced flow

For handling unbalanced flow of messages merge both of your poller Lambdas. Implement one Lambda that polls both queues for MaxNumberOfMessages (that equals 100% of the limits of both). In this implementation send from your poller Lambda 90% of campaign1 messages and 10% of campaign2 messages. When campaign2 no longer has messages to process, keep processing 100% of the capacity from campaign1’s queue.

Do not delete unsent messages from the queues. These messages will become visible after their queue’s visibility timeout is reached.

To further improve on the previous implementations, introduce a third FIFO Queue to aggregate all messages from both queues and regulate dequeuing from that third FIFO queue. This will allow you to use all available capacity under your SES limit, while interweaving messages from both campaigns at a 1:10 ratio.

Fig 5 — Adding FIFO merge queue diagram

Processing 100% of the available capacity limit of the large campaign1 and 10% of the capacity limit of the small campaign2 allows you to make sure campign2 messages will not wait until campaign1 messages were all processed. Once campain2 messages are all processed, campign1 messages will continue to be processed using 100% of the capacity limit.

You can find here instructions for Configuring Amazon SQS queues.

Conclusion

In this blog post, we have shown you how to regulate the dequeue of Amazon SQS queue messages. This will prevent you from exceeding your Amazon SES per second limit. This will also remove the need to deal with throttled requests. We explained how to combine Amazon SQS, AWS Lambda, Amazon EventBridge to create a custom serverless regulating queue poller. Finally, we described how to regulate the flow of Amazon SES requests when using multiple priority queues. These technics can reduce implementation time for reprocessing throttled requests, optimize utilization of SES request limit, and reduce costs.

About the Authors

This blog post was written by Guy Loewy and Mark Richman, AWS Senior Solutions Architects for SMB.

How USAA built an Amazon S3 malware scanning solution

Post Syndicated from Jonathan Nguyen original https://aws.amazon.com/blogs/architecture/how-usaa-built-an-amazon-s3-malware-scanning-solution/

United Services Automobile Association (USAA) is a San Antonio-based insurance, financial services, banking, and FinTech company supporting millions of military members and their families. USAA has partnered with Amazon Web Services (AWS) to digitally transform and build multiple USAA solutions that help keep members safe and save members money and time.

Why build a S3 malware scanning solution?

As complex companies’ businesses continue to grow, there may be an increased need for collaboration and interactions with outside vendors. Prior to developing an Amazon Simple Storage Solution (Amazon S3) scanning solution, a security review and approval process for application teams to ingest data into an AWS Organization from external vendors’ AWS accounts may be warranted, to ensure additional threats are not being introduced. This could result in a lengthy review and exception process, and subsequently, could hinder the velocity of application teams’ collaboration with external vendors.

USAA security standards, like those of most companies, require all data from external vendors to be treated as untrusted, and therefore must be scanned by an antivirus or antimalware solution prior to being ingested by downstream processes within the AWS environment. Companies looking to automate the scanning process may want to consider a solution where all incoming external data flow through a demilitarized drop zone to be scanned, and subsequently released to downstream processes if malware and viruses are not detected.

S3 malware scanning solution overview

Dedicated AWS accounts should be provisioned for specific data classifications and used as a demilitarized zone (DMZ) for an untrusted staging area. The solution discussed in this blog uses a dedicated staging AWS account that controls the release of Amazon S3 objects to other AWS accounts within an AWS Organization. AWS accounts within an AWS Organization should follow security best practices in terms of infrastructure, networking, logging, and security. External vendors should explicitly be given limited permissions to appropriate resources in their respective staging S3 bucket.

A staging S3 bucket should have specific resource policies restricting which applications and identity and access management (IAM) principals can interact with S3 objects using object attributes, such as object tags, to determine whether an object has been scanned, and what the results of that scan are. Additional guardrails are implemented using Service Control Policies (SCP) to restrict authorized IAM principals to create or modify S3 object attributes (Figure 1).

Amazon S3 antivirus and antimalware scanning architecture workflow

Figure 1. Amazon S3 antivirus and antimalware scanning architecture workflow

  1. The external vendor copies an object to the staging S3 bucket.
  2. The staging S3 bucket has event notifications configured and generates an event.
  3. The S3 PutObject event is sent to an Object Created Amazon Simple Queue Service (Amazon SQS) queue topic.
  4. An Amazon Elastic Compute Cloud (Amazon EC2) Auto Scaling group is configured to scale based on messages in the Object Created SQS queue.
  5. An antivirus and antimalware scanning service application on the Amazon EC2 instances takes the following actions on objects within the Object Created Amazon SQS queue:
    a. Tag the S3 object with an “In Progress” status.
    b. Get the object from the Staging S3 bucket and stores it in a local ephemeral file system.
    c. Scan the copied object using antivirus or antimalware tool.
    d. Based on the antivirus or antimalware scan results, tag the S3 object with the scan results (for example, No_Malware_Detected vs. Malware_Detected).
    e. Create and publish a payload to the Object Scanned Amazon Simple Notification Service (Amazon SNS) topic, allowing application team filtering.
    f. Delete the message from the Object Created SQS queue.
  6. Application teams are subscribed to the Object Scanned SNS topic with a filter for their application.
  7. For any objects where a virus or malware is detected, a company can use its cyber threat response team to conduct a thorough analysis and take appropriate actions.

USAA built a custom anti-virus and anti-malware scanning application using EC2 instances, using a private, hardened Amazon Machine Image (AMI). For cost-efficacy purposes, the EC2 automatic scaling event can be configured based on Object Created SQS queue depth and Service Level Objective (SLO). A serverless version of an anti-virus and anti-malware solution can be used instead of an EC2 application, depending on your specific use-case and other factors. Some important factors include antivirus and antimalware tool serverless support, resource tuning and configuration requirements, and additional AWS services to manage that could possibly result in a bottleneck. If your enterprise is going with a serverless approach, you can use open-source tools such as ClamAV using Lambda functions.

In the event of an infected object, proper guardrails and response mechanisms need to be in place. USAA teams have developed playbooks to monitor the health and performance of S3 scanning solution, as well as responding to detected virus or malware.

This cloud native, event-driven solution has benefited multiple USAA application teams who have previously requested the ability to ingest data into AWS workloads from teams outside of USAA’s AWS Organization, and allowed additional capabilities and functionality to better serve their members. To enhance this solution even further, USAA’s security team plans to incorporate additional mechanisms to find specific objects that either failed or required additional processing, without having to scan all objects in the buckets. This can be accomplished by including an additional AWS Lambda function and Amazon DynamoDB table to track object metadata as objects get added to the Object Created SQS queue for processing. The metadata could possibly include information such as S3 bucket origin, S3 object key, version ID, scan status, and the original S3 event payload to replay the event into the Object Created SQS queue. The Lambda function primarily ensures the DynamoDB table is kept up to date as objects are processed, as well as handling issues for objects that may need to be reprocessed. The DynamoDB table also has time-to-live (TTL) configured to clear records as they expire from the Staging S3 bucket.

Conclusion

In this post, we reviewed how USAA’s Public Cloud Security team facilitated collaboration and interactions with external vendors and AWS workloads securely by creating a scalable solution to scan S3 objects for virus and malware prior to releasing objects downstream. The solution uses native AWS services and can be utilized for any use-cases requiring antivirus or antimalware capabilities. Because the S3 object scanning solution uses EC2 instances, you can use your existing antivirus or antimalware enterprise tool.

How a blockchain startup built a prototype solution to solve the need of analytics for decentralized applications with AWS Data Lab

Post Syndicated from Dr. Quan Hoang Nguyen original https://aws.amazon.com/blogs/big-data/how-a-blockchain-startup-built-a-prototype-solution-to-solve-the-need-of-analytics-for-decentralized-applications-with-aws-data-lab/

This post is co-written with Dr. Quan Hoang Nguyen, CTO at Fantom Foundation.

Here at Fantom Foundation (Fantom), we have developed a high performance, highly scalable, and secure smart contract platform. It’s designed to overcome limitations of the previous generation of blockchain platforms. The Fantom platform is permissionless, decentralized, and open source. The majority of decentralized applications (dApps) hosted on the Fantom platform lack an analytics page that provides information to the users. Therefore, we would like to build a data platform that supports a web interface that will be made public. This will allow users to search for a smart contract address. The application then displays key metrics for that smart contract. Such an analytics platform can give insights and trends for applications deployed on the platform to the users, while the developers can continue to focus on improving their dApps.

AWS Data Lab offers accelerated, joint-engineering engagements between customers and AWS technical resources to create tangible deliverables that accelerate data and analytics modernization initiatives. Data Lab has three offerings: the Build Lab, the Design Lab, and a Resident Architect. The Build Lab is a 2–5 day intensive build with a technical customer team. The Design Lab is a half-day to 2-day engagement for customers who need a real-world architecture recommendation based on AWS expertise, but aren’t yet ready to build. Both engagements are hosted either online or at an in-person AWS Data Lab hub. The Resident Architect provides AWS customers with technical and strategic guidance in refining, implementing, and accelerating their data strategy and solutions over a 6-month engagement.

In this post, we share the experience of our engagement with AWS Data Lab to accelerate the initiative of developing a data pipeline from an idea to a solution. Over 4 weeks, we conducted technical design sessions, reviewed architecture options, and built the proof of concept data pipeline.

Use case review

The process started with us engaging with our AWS Account team to submit a nomination for the data lab. This followed by a call with the AWS Data Lab team to assess the suitability of requirements against the program. After the Build Lab was scheduled, an AWS Data Lab Architect engaged with us to conduct a series of pre-lab calls to finalize the scope, architecture, goals, and success criteria for the lab. The scope was to design a data pipeline that would ingest and store historical and real-time on-chain transactions data, and build a data pipeline to generate key metrics. Once ingested, data should be transformed, stored, and exposed via REST-based APIs and consumed by a web UI to display key metrics. For this Build Lab, we choose to ingest data for Spooky, which is a decentralized exchange (DEX) deployed on the Fantom platform and had the largest Total Value Locked (TVL) at that time. Key metrics such number of wallets that have interacted with the dApp over time, number of tokens and their value exchanged for the dApp over time, and number of transactions for the dApp over time were selected to visualize through a web-based UI.

We explored several architecture options and picked one for the lab that aligned closely with our end goal. The total historical data for the selected smart contract was approximately 1 GB since deployment of dApp on the Fantom platform. We used FTMScan, which allows us to explore and search on the Fantom platform for transactions, to estimate the rate of transfer transactions to be approximately three to four per minute. This allowed us to design an architecture for the lab that can handle this data ingestion rate. We agreed to use an existing application known as the data producer that was developed internally by the Fantom team to ingest on-chain transactions in real time. On checking transactions’ payload size, it was found to not exceed 100 kb for each transaction, which gave us the measure of number of files that will be created once ingested through the data producer application. A decision was made to ingest the past 45 days of historic transactions to populate the platform with enough data to visualize key metrics. Because the feature of backdating exists within the data producer application, we agreed to use that. The Data Lab Architect also advised us to consider using AWS Database Migration Service (AWS DMS) to ingest historic transactions data post lab. As a last step, we decided to build a React-based webpage with Material-UI that allows users to enter a smart contract address and choose the time interval, and the app fetches the necessary data to show the metrics value.

Solution overview

We collectively agreed to incorporate the following design principles for the data lab architecture:

  • Simplified data pipelines
  • Decentralized data architecture
  • Minimize latency as much as possible

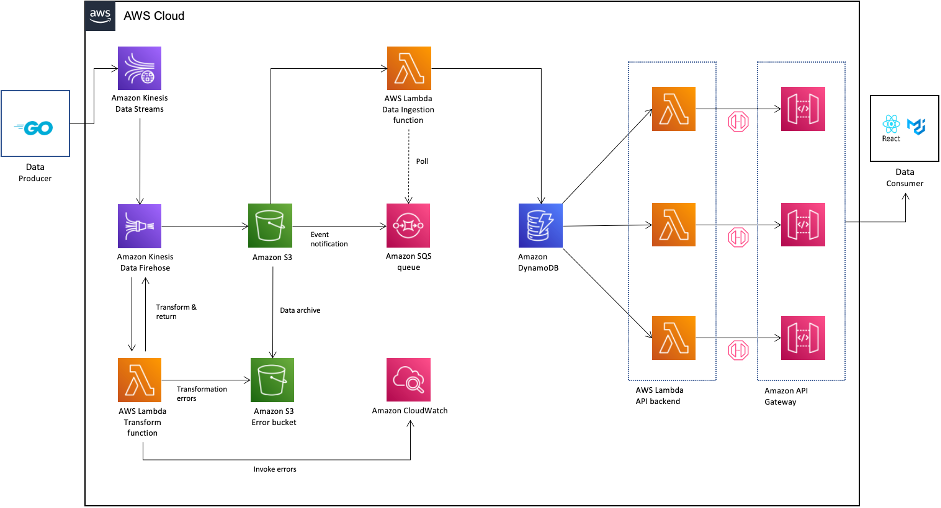
The following diagram illustrates the architecture that we built in the lab.

We collectively defined the following success criteria for the Build Lab:

  • End-to-end data streaming pipeline to ingest on-chain transactions
  • Historical data ingestion of the selected smart contract
  • Data storage and processing of on-chain transactions
  • REST-based APIs to provide time-based metrics for the three defined use cases
  • A sample web UI to display aggregated metrics for the smart contract

Prior to the Build Lab

As a prerequisite for the lab, we configured the data producer application to use the AWS Software Development Kit (AWS SDK) and PUTRecords API operation to send transactions data to an Amazon Simple Storage Service (Amazon S3) bucket. For the Build Lab, we built additional logic within the application to ingest historic transactions data together with real-time transactions data. As a last step, we verified that transactions data was captured and ingested into a test S3 bucket.

AWS services used in the lab

We used the following AWS services as part of the lab:

  • AWS Identity and Access Management (IAM) – We created multiple IAM roles with appropriate trust relationships and necessary permissions that can be used by multiple services to read and write on-chain transactions data and generated logs.
  • Amazon S3 – We created an S3 bucket to store the incoming transactions data as JSON-based files. We created a separate S3 bucket to store incoming transaction data that failed to be transformed and will be reprocessed later.
  • Amazon Kinesis Data Streams – We created a new Kinesis data stream in on-demand mode, which automatically scales based on data ingestion patterns and provides hands-free capacity management. This stream was used by the data producer application to ingest historical and real-time on-chain transactions. We discussed having the ability to manage and predict cost, and therefore were advised to use the provisioned mode when reliable estimates were available for throughput requirements. We were also advised to continue to use on-demand mode until the data traffic patterns were unpredictable.
  • Amazon Kinesis Data Firehose – We created a Firehose delivery stream to transform the incoming data and writes it to the S3 bucket. To minimize latency, we set the delivery stream buffer size to 1 MiB and buffer interval to 60 seconds. This would ensure a file is written to the S3 bucket when either of the two conditions are satisfied regardless of the order. Transactions data written to the S3 bucket was in JSON Lines format.
  • Amazon Simple Queue Service (Amazon SQS) – We set up an SQS queue of the type Standard and an access policy for that SQS queue to allow incoming messages generated from S3 bucket event notifications.
  • Amazon DynamoDB – In order to pick a data store for on-chain transactions, we needed a service that can store transactions payload of unstructured data with varying schemas, provides the ability to cache query results, and is a managed service. We picked DynamoDB for those reasons. We created a single DynamoDB table that holds the incoming transactions data. After analyzing the access query patterns, we decided to use the address field of the smart contract as the partition key and the timestamp field as the sort key. The table was created with auto scaling of read and write capacity modes because the actual usage requirements would be hard to predict at that time.
  • AWS Lambda – We created the following functions:
    • A Python-based Lambda function to perform transformations on the incoming data from the data producer application to flatten the JSON structure, convert the Unix-based epoch timestamp to a date/time value, and convert hex-based string values to a decimal value representing the number of tokens.
    • A second Lambda function to parse incoming SQS queue messages. This message contained values for bucket_name and object_key, which holds the reference to a newly created object within the S3 bucket. The Lambda function logic included parsing of this value to obtain the reference to the S3 object, get the contents of the object, read it into a data frame object using the AWS SDK for pandas (awswrangler) library, convert it into a Pandas data frame object, and use the put_df API call to write a Pandas data frame object as an item into a DynamoDB table. We choose to use Pandas due to familiarity with the library and functions required to perform data transform operations.
    • Three separate Lambda functions that contains the logic to query the DynamoDB table and retrieve items to aggregate and calculate metrics values. This calculated metrics value within the Lambda function was formatted as an HTTP response to expose as REST-based APIs.
  • Amazon API Gateway – We created a REST based API endpoint that uses Lambda proxy integration to pass a smart contract address and time-based interval in minutes as a query string parameter to the backend Lambda function. The response from the Lambda function was a metrics value. We also enabled cross-origin resource sharing (CORS) support within API Gateway to successfully query from the web UI that resides in a different domain.
  • Amazon CloudWatch – We used a Lambda function in-built mechanism to send function metrics to CloudWatch. Lambda functions come with a CloudWatch Logs log group and a log stream for each instance of your function. The Lambda runtime environment sends details of each invocation to the log stream, and relays logs and other output from your function’s code.

Iterative development approach

Across 4 days of the Build Lab, we undertook iterative development. We started by developing the foundational layer and iteratively added extra features through testing and data validation. This allowed us to develop confidence of the solution being built as we tested the output of the metrics through a web-based UI and verified with the actual data. As errors got discovered, we deleted the entire dataset and reran all the jobs to verify results and resolve those errors.

Lab outcomes

In 4 days, we built an end-to-end streaming pipeline ingesting 45 days of historical data and real-time on-chain transactions data for the selected Spooky smart contract. We also developed three REST-based APIs for the selected metrics and a sample web UI that allows users to insert a smart contract address, choose a time frequency, and visualize the metrics values. In a follow-up call, our AWS Data Lab Architect shared post-lab guidance around the next steps required to productionize the solution:

  • Scaling of the proof of concept to handle larger data volumes
  • Security best practices to protect the data while at rest and in transit
  • Best practices for data modeling and storage
  • Building an automated resilience technique to handle failed processing of the transactions data
  • Incorporating high availability and disaster recovery solutions to handle incoming data requests, including adding of the caching layer

Conclusion

Through a short engagement and small team, we accelerated this project from an idea to a solution. This experience gave us the opportunity to explore AWS services and their analytical capabilities in-depth. As a next step, we will continue to take advantage of AWS teams to enhance the solution built during this lab to make it ready for the production deployment.

Learn more about how the AWS Data Lab can help your data and analytics on the cloud journey.


About the Authors

Dr. Quan Hoang Nguyen is currently a CTO at Fantom Foundation. His interests include DLT, blockchain technologies, visual analytics, compiler optimization, and transactional memory. He has experience in R&D at the University of Sydney, IBM, Capital Markets CRC, Smarts – NASDAQ, and National ICT Australia (NICTA).

Ankit Patira is a Data Lab Architect at AWS based in Melbourne, Australia.

AWS Week in Review – October 24, 2022

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/aws-week-in-review-october-24-2022/

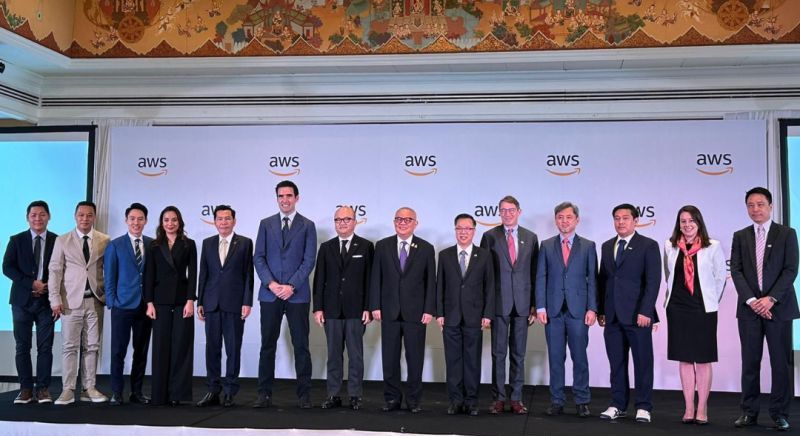
Last week, we announced plans to launch the AWS Asia Pacific (Bangkok) Region, which will become our third AWS Region in Southeast Asia. This Region will have three Availability Zones and will give AWS customers in Thailand the ability to run workloads and store data that must remain in-country.

In the Works – AWS Region in Thailand
With this big news, AWS announced a 190 billion baht (US 5 billion dollars) investment to drive Thailand’s digital future over the next 15 years. It includes capital expenditures on the construction of data centers, operational expenses related to ongoing utilities and facility costs, and the purchase of goods and services from Regional businesses.

Since we first opened an office in Bangkok in 2015, AWS has launched 10 Amazon CloudFront edge locations, a highly secure and programmable content delivery network (CDN) in Bangkok. In 2020, we launched AWS Outposts, a family of fully managed solutions delivering AWS infrastructure and services to virtually any on-premises or edge location for a truly consistent hybrid experience in Thailand. This year, we also plan the upcoming launch of an AWS Local Zone in Bangkok, which will enable customers to deliver applications that require single-digit millisecond latency to end users in Thailand.

Photo courtesy of Conor McNamara, Managing Director, ASEAN at AWS

The new AWS Region in Thailand is also part of our broader, multifaceted investment in the country, covering our local team, partners, skills, and the localization of services, including Amazon Transcribe, Amazon Translate, and Amazon Connect.

Many Thailand customers have chosen AWS to run their workloads to accelerate innovation, increase agility, and drive cost savings, such as 2C2P, CP All Plc., Digital Economy Promotion Agency, Energy Response Co. Ltd. (ENRES), PTT Global Public Company Limited (PTT), Siam Cement Group (SCG), Sukhothai Thammathirat Open University, The Stock Exchange of Thailand, Papyrus Studio, and more.

For example, Dr. Werner Vogels, CTO of Amazon.com, introduced the story of Papyrus Studio, a large film studio and one of the first customers in Thailand.

“Customer stories like Papyrus Studio inspire us at AWS. The cloud can allow a small company to rapidly scale and compete globally. It also provides new opportunities to create, innovate, and identify business opportunities that just aren’t possible with conventional infrastructure.”

For more information on how to enable AWS and get support in Thailand, contact our AWS Thailand team.

Last Week’s Launches
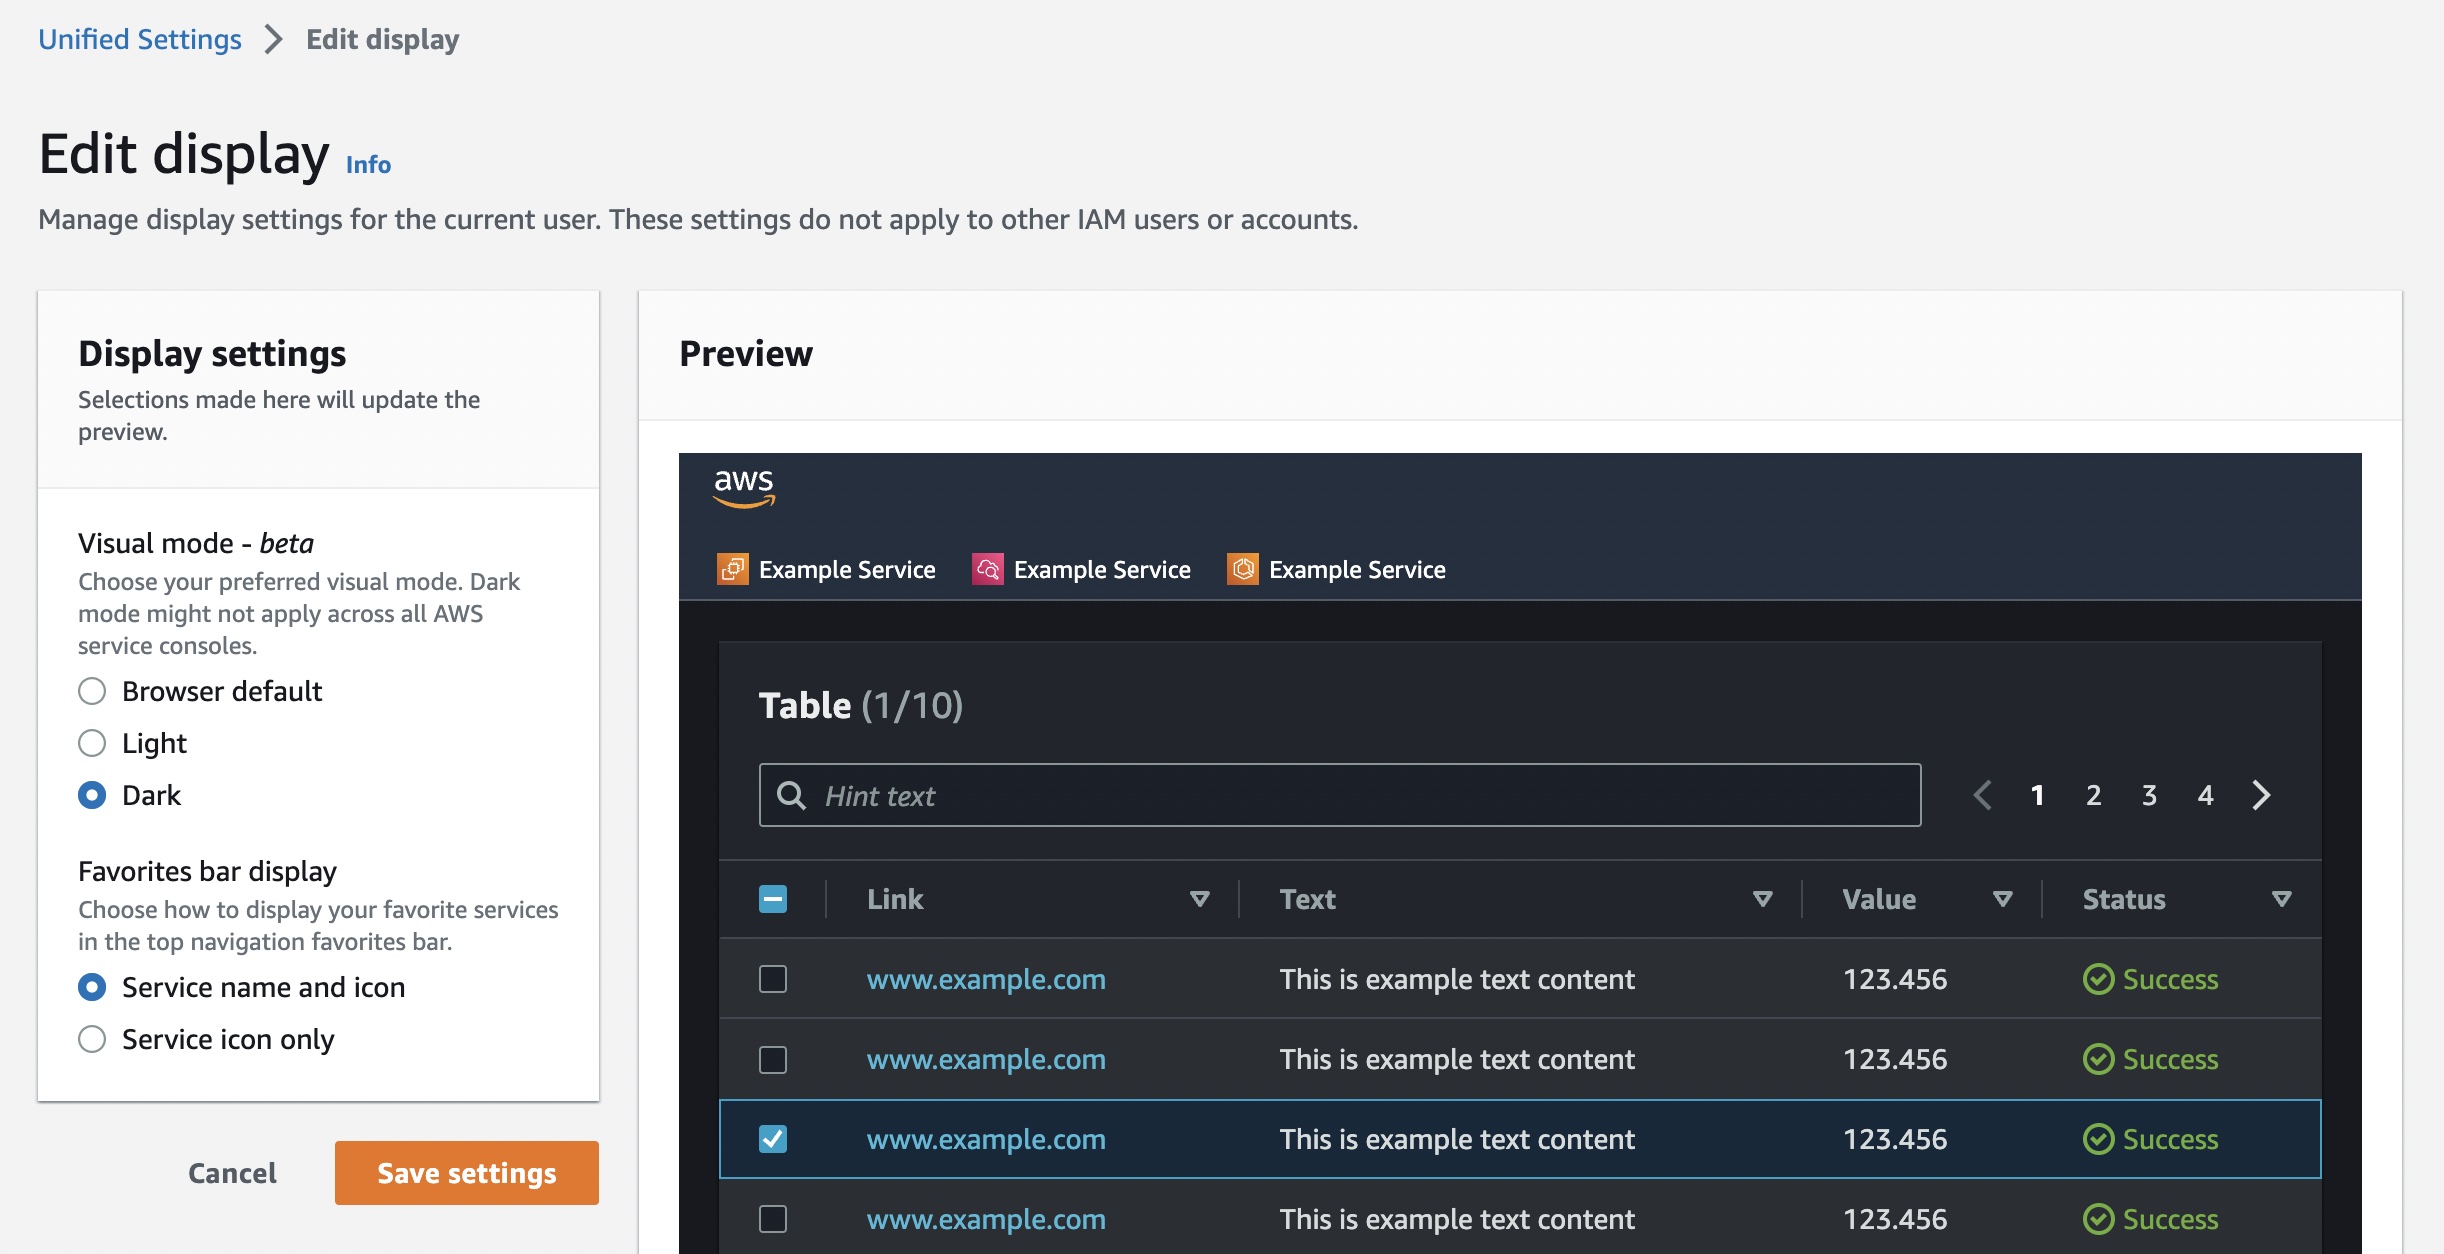
My favorite news of last week was to launch dark mode as a beta feature in the AWS Management Console. In Unified Settings, you can choose between three settings for visual mode: Browser default, Light, and Dark. Browser default applies the default dark or light setting of the browser, dark applies the new built-in dark mode, and light maintains the current look and feel of the AWS console. Choose your favorite!

Here are some launches that caught my eye for web, mobile, and IoT application developers:

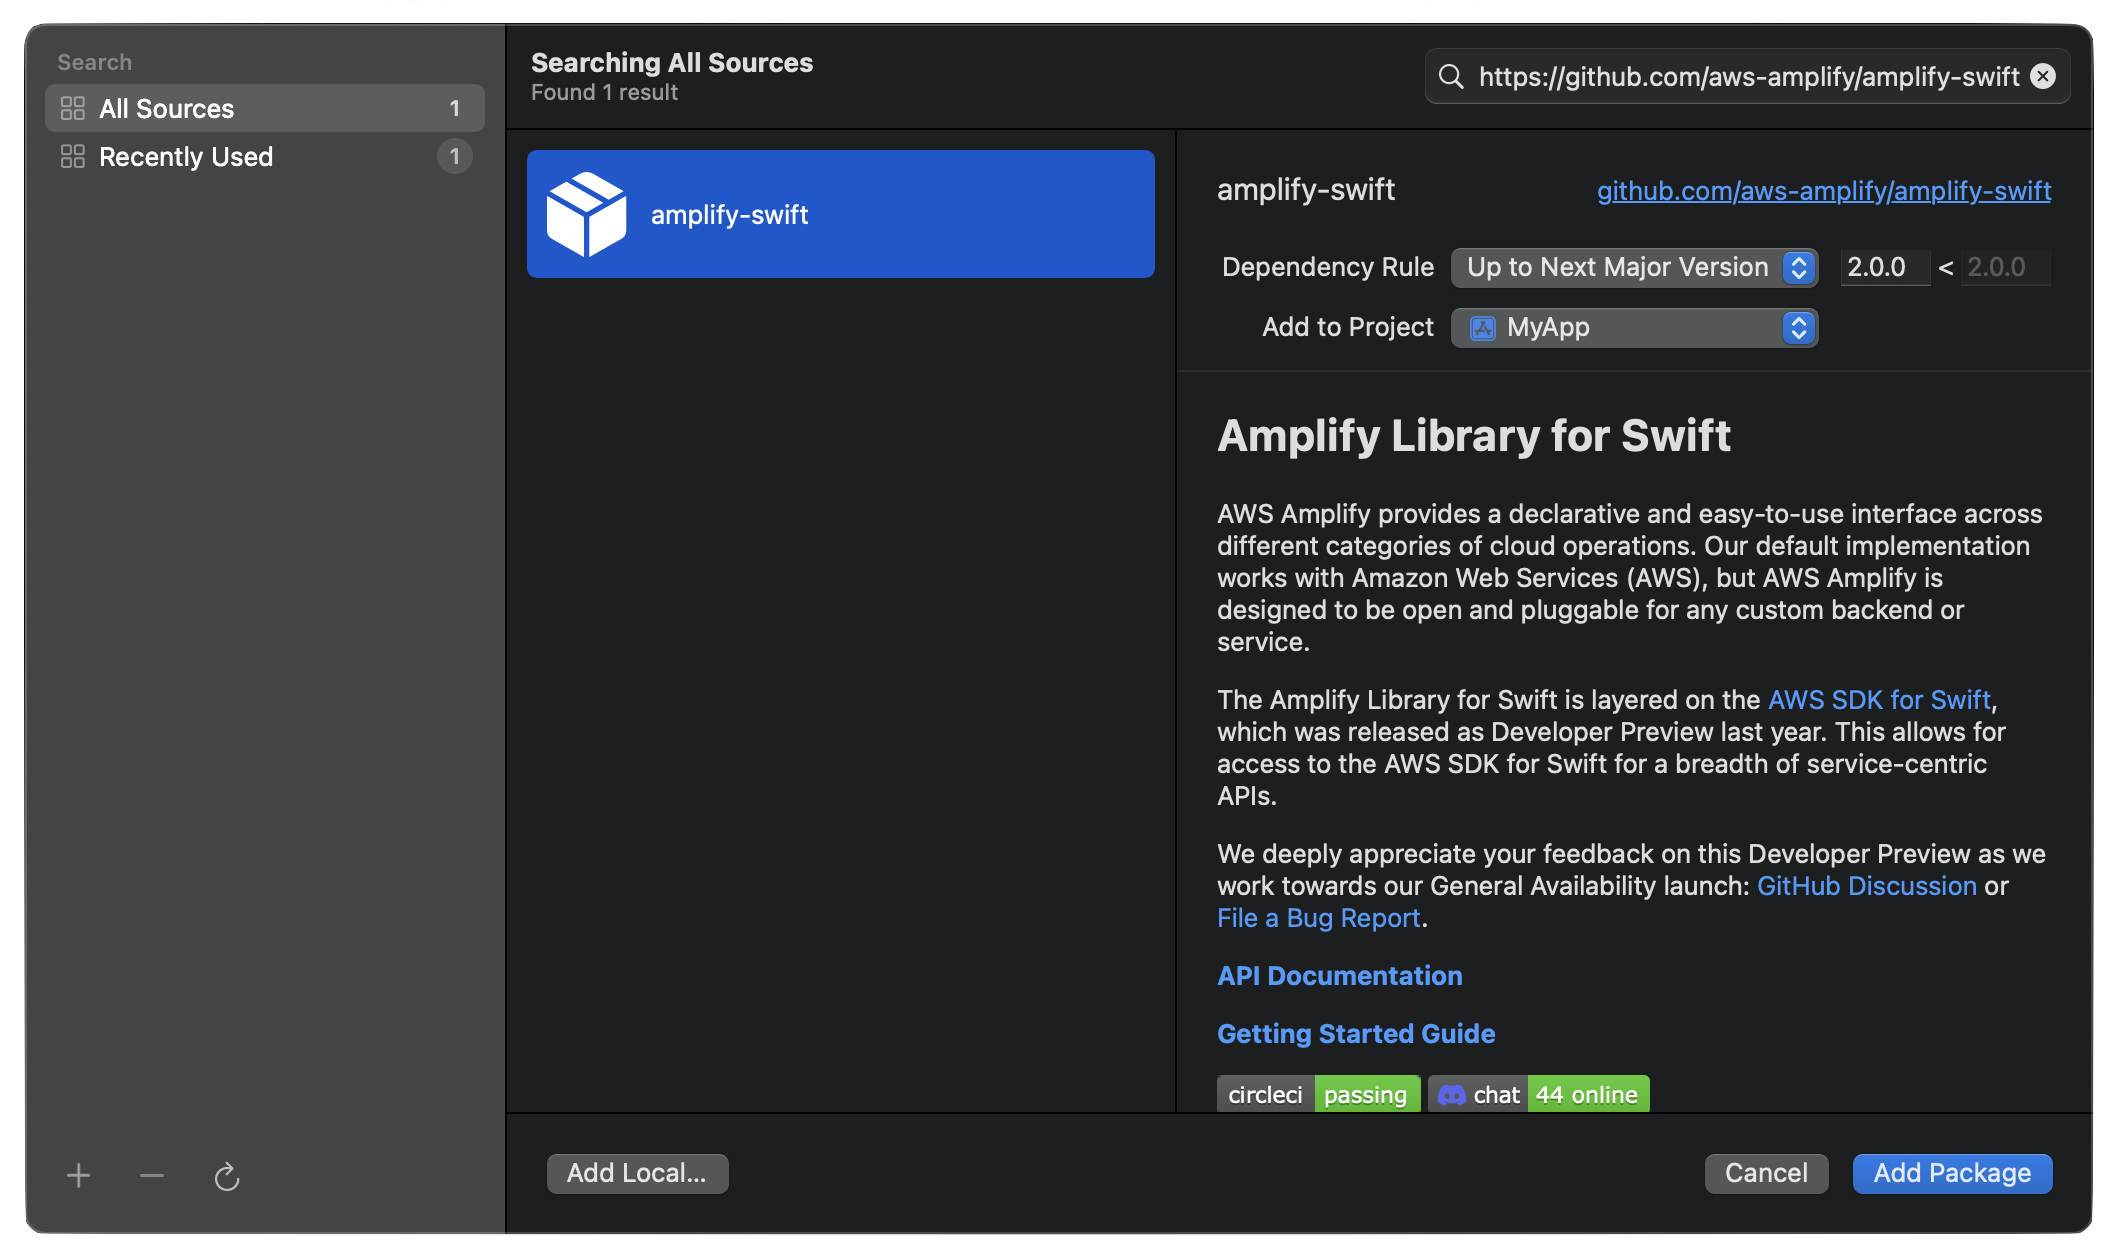
New AWS Amplify Library for Swift – We announce the general availability of Amplify Library for Swift (previously Amplify iOS). Developers can use Amplify Library for Swift via the Swift Package Manager to build apps for iOS and macOS (currently in beta) platforms with Auth, Storage, Geo, and more features.

The Amplify Library for Swift is open source on GitHub, and we deeply appreciate the feedback we have gotten from the community. To learn more, see Introducing the AWS Amplify Library for Swift in the AWS Front-End Web & Mobile Blog or Amplify Library for Swift documentation.

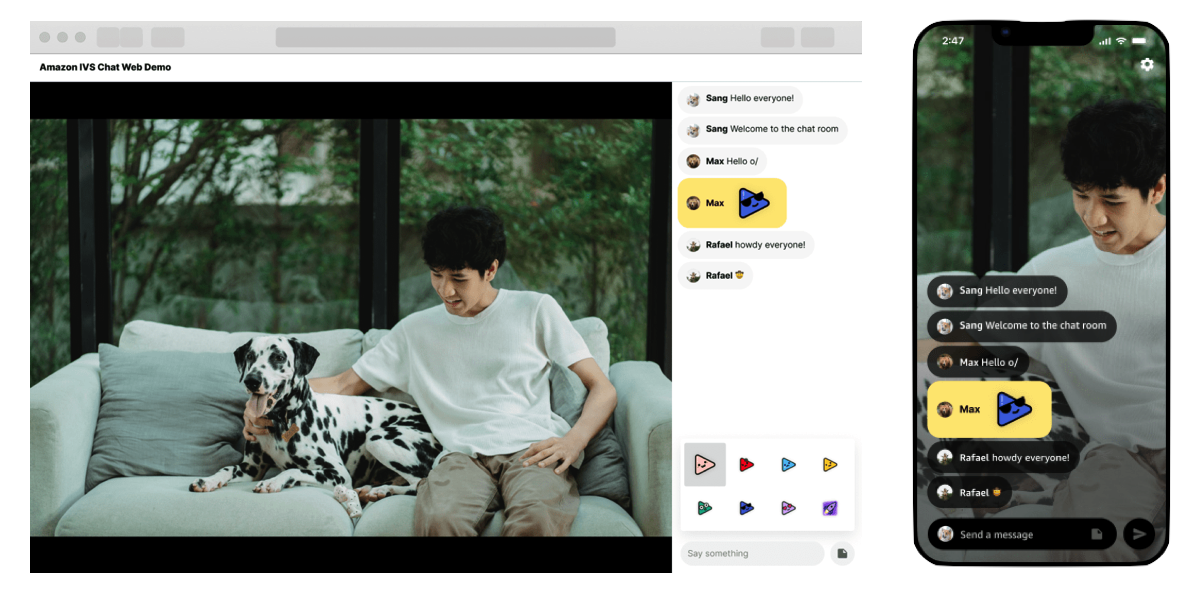
New Amazon IVS Chat SDKs – Amazon Interactive Video Service (Amazon IVS) now provides SDKs for stream chat with support for web, Android, and iOS. The Amazon IVS stream chat SDKs support common functions for chat room resource management, sending and receiving messages, and managing chat room participants.

Amazon IVS is a managed, live-video streaming service using the broadcast SDKs or standard streaming software such as Open Broadcaster Software (OBS). The service provides cross-platform player SDKs for playback of Amazon IVS streams you need to make low-latency live video available to any viewer around the world. Also, it offers Chat Client Messaging SDK. For more information, see Getting Started with Amazon IVS Chat in the AWS documentation.

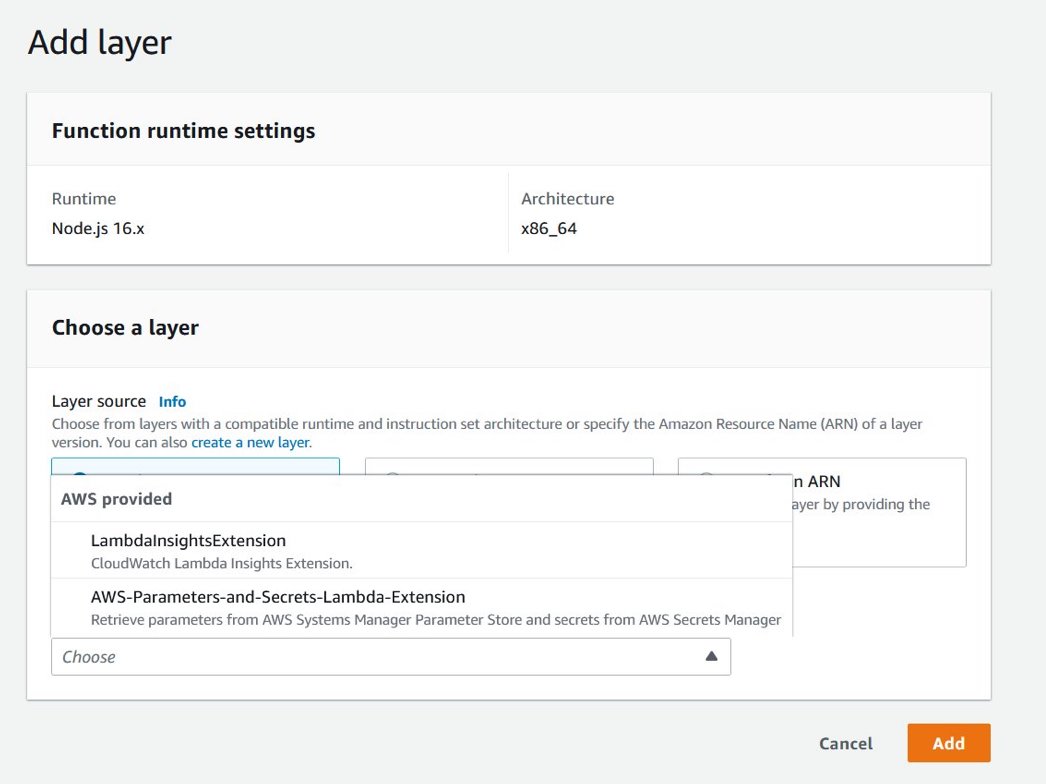
New AWS Parameters and Secrets Lambda Extension – This is new extension for AWS Lambda developers to retrieve parameters from AWS Systems Manager Parameter Store and secrets from AWS Secrets Manager. Lambda function developers can leverage this extension to improve their application performance as it decreases the latency and the cost of retrieving parameters and secrets.

Previously, you had to initialize either the core library of a service or the entire service SDK inside a Lambda function for retrieving secrets and parameters. Now you can simply use the extension. To learn more, see AWS Systems Manager Parameter Store documentation and AWS Secrets Manager documentation.

New FreeRTOS Long Term Support Version – We announce the second release of FreeRTOS Long Term Support (LTS) – FreeRTOS 202210.00 LTS. FreeRTOS LTS offers a more stable foundation than standard releases as manufacturers deploy and later update devices in the field. This release includes new and upgraded libraries such as AWS IoT Fleet Provisioning, Cellular LTE-M Interface, coreMQTT, and FreeRTOS-Plus-TCP.

All libraries included in this FreeRTOS LTS version will receive security and critical bug fixes until October 2024. With an LTS release, you can continue to maintain your existing FreeRTOS code base and avoid any potential disruptions resulting from FreeRTOS version upgrades. To learn more, see the FreeRTOS announcement.

Here is some news on performance improvement and increasing capacity:

Up to 10X Improving Amazon Aurora Snapshot Exporting Speed – Amazon Aurora MySQL-Compatible Edition for MySQL 5.7 and 8.0 now speed up to 10x faster snapshot exports to Amazon S3. The performance improvement is automatically applied to all types of database snapshot exports, including manual snapshots, automated system snapshots, and snapshots created by the AWS Backup service. For more information, see Exporting DB cluster snapshot data to Amazon S3 in the Amazon Aurora documentation.

3X Increasing Amazon RDS Read Capacity – Amazon Relational Database Service (RDS) for MySQL, MariaDB, and PostgreSQL now supports 15 read replicas per instance, including up to 5 cross-Region read replicas, delivering up to 3x the previous read capacity. For more information, see Working with read replicas in the Amazon RDS documentation.

2X Increasing AWS Snowball Edge Compute Capacity – The AWS Snowball Edge Compute Optimized device doubled the compute capacity up to 104 vCPUs, doubled the memory capacity up to 416GB RAM, and is now fully SSD with 28TB NVMe storage. The updated device is ideal when you need dense compute resources to run complex workloads such as machine learning inference or video analytics at the rugged, mobile edge such as trucks, aircraft or ships.  You can get started by ordering a Snowball Edge device on the AWS Snow Family console.

2X Increasing Amazon SQS FIFO Default Quota – Amazon Simple Queue Service (SQS) announces the increase of default quota up to 6,000 transactions per second per API action. It is double the previous 3,000 throughput quota for a high throughput mode for FIFO (first in, first out) queues in all AWS Regions where Amazon SQS FIFO queue is available. For a detailed breakdown of default throughput quotas per Region, see Quotas related to messages in the Amazon SQS documentation.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
Here are some other news items that you may find interesting:

22 New or Updated Open Datasets on AWS – We released 22 new or updated datasets, including Amazonia-1 imagery, Bitcoin and Ethereum data, and elevation data over the Arctic and Antarctica. The full list of publicly available datasets is on the Registry of Open Data on AWS and is now also discoverable on AWS Data Exchange.

Sustainability with AWS Partners (ft. AWS On Air) – This episode covers a broad discipline of environmental, social, and governance (ESG) issues across all regions, organization types, and industries. AWS Sustainability & Climate Tech provides a comprehensive portfolio of AWS Partner solutions built on AWS that address climate change events and the United Nation’s Sustainable Development Goals (SDG).

AWS Open Source News and Updates #131 – This newsletter covers latest open-source projects such as Amazon EMR Toolkit for VS Code, a VS Code Extension to make it easier to develop Spark jobs on EMR and AWS CDK For Discourse, sample codes that demonstrates how to create a full environment for Discourse, etc. Remember to check out the Open source at AWS keep up to date with all our activity in open source by following us on @AWSOpen.

Upcoming AWS Events
Check your calendars and sign up for these AWS events:

AWS re:Invent 2022 Attendee Guide – Browse re:Invent 2022 attendee guides, curated by AWS Heroes, AWS industry teams, and AWS Partners. Each guide contains recommended sessions, tips and tricks for building your agenda, and other useful resources. Also, seat reservations for all sessions are now open for all re:Invent attendees. You can still register for AWS re:Invent either offline or online.

AWS AI/ML Innovation Day on October 25 – Join us for this year’s AWS AI/ML Innovation Day, where you’ll hear from Bratin Saha and other leaders in the field about the great strides AI/ML has made in the past and the promises awaiting us in the future.

AWS Container Day at Kubecon 2022 on October 25–28 – Come join us at KubeCon + CloudNativeCon North America 2022, where we’ll be hosting AWS Container Day Featuring Kubernetes on October 25 and educational sessions at our booth on October 26–28. Throughout the event, our sessions focus on security, cost optimization, GitOps/multi-cluster management, hybrid and edge compute, and more.

You can browse all upcoming in-person, and virtual events.

That’s all for this week. Check back next Monday for another Week in Review!

— Channy

This post is part of our Week in Review series. Check back each week for a quick roundup of interesting news and announcements from AWS!

Adding approval notifications to EC2 Image Builder before sharing AMIs

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/adding-approval-notifications-to-ec2-image-builder-before-sharing-amis-2/

­­­­­This blog post is written by, Glenn Chia Jin Wee, Associate Cloud Architect, and Randall Han, Professional Services.

You may be required to manually validate the Amazon Machine Image (AMI) built from an Amazon Elastic Compute Cloud (Amazon EC2) Image Builder pipeline before sharing this AMI to other AWS accounts or to an AWS organization. Currently, Image Builder provides an end-to-end pipeline that automatically shares AMIs after they’ve been built.

In this post, we will walk through the steps to enable approval notifications before AMIs are shared with other AWS accounts. Image Builder supports automated image testing using test components. The recommended best practice is to automate test steps, however situations can arise where test steps become either challenging to automate or internal compliance policies mandate manual checks be conducted prior to distributing images. In such situations, having a manual approval step is useful if you would like to verify the AMI configuration before it is shared to other AWS accounts or an AWS Organization. A manual approval step reduces the potential for sharing an incorrectly configured AMI with other teams which can lead to downstream issues. This solution sends an email with a link to approve or reject the AMI. Users approve the AMI after they’ve verified that it is built according to specifications. Upon approving the AMI, the solution automatically shares it with the specified AWS accounts.

OverviewArchitecture Diagram

  1. In this solution, an Image Builder Pipeline is run that builds a Golden AMI in Account A. After the AMI is built, Image Builder publishes data about the AMI to an Amazon Simple Notification Service (Amazon SNS)
  2. The SNS Topic passes the data to an AWS Lambda function that subscribes to it.
  3. The Lambda function that subscribes to this topic retrieves the data, formats it, and then starts an SSM Automation, passing it the AMI Name and ID.
  4. The first step of the SSM Automation is a manual approval step. The SSM Automation first publishes to an SNS Topic that has an email subscription with the Approver’s email. The approver will receive the email with a URL that they can click to approve the step.
  5. The approval step defines a specific AWS Identity and Access Management (IAM) Role as an approver. This role has the minimum required permissions to approve the manual approval step. After performing manual tests on the Golden AMI, the Approver principal will assume this role.
  6. After assuming this role, the approver will click on the approval link that was sent via email. After approving the step, an AWS Lambda Function is triggered.
  7. This Lambda Function shares the Golden AMI with Account B and sends an email notifying the Target Account Recipients that the AMI has been shared.

Prerequisites

For this walkthrough, you will need the following:

  • Two AWS accounts – one to host the solution resources, and the second which receives the shared Golden AMI.
    • In the account that hosts the solution, prepare an AWS Identity and Access Management (IAM) principal with the sts:AssumeRole permission. This principal must assume the IAM Role that is listed as an approver in the Systems Manager approval step. The ARN of this IAM principal is used in the AWS CloudFormation Approver parameter, This ARN is added to the trust policy of approval IAM Role.
    • In addition, in the account hosting the solution, ensure that the IAM principal deploying the CloudFormation template has the required permissions to create the resources in the stack.
  • A new Amazon Virtual Private Cloud (Amazon VPC) will be created from the stack. Make sure that you have fewer than five VPCs in the selected Region.

Walkthrough

In this section, we will guide you through the steps required to deploy the Image Builder solution. The solution is deployed with CloudFormation.

In this scenario, we deploy the solution within the approver’s account. The approval email will be sent to a predefined email address for manual approval, before the newly created AMI is shared to target accounts.

The approver first assumes the approval IAM Role and then selects the approval link. This leads to the Systems Manager approval page. Upon approval, an email notification will be sent to the predefined target account email address, notifying the relevant stakeholders that the AMI has been successfully shared.

The high-level steps we will follow are:

  1. In Account A, deploy the provided AWS CloudFormation template. This includes an example Image Builder Pipeline, Amazon SNS topics, Lambda functions, and an SSM Automation Document.
  2. Approve the SNS subscription from your supplied email address.
  3. Run the pipeline from the Amazon EC2 Image Builder Console.
  4. [Optional] To conduct manual tests, launch an Amazon EC2 instance from the built AMI after the pipeline runs.
  5. An email will be sent to you with options to approve or reject the step. Ensure that you have assumed the IAM Role that is the approver before clicking the approval link that leads to the SSM console approval page.
  6. Upon approving the step, an AWS Lambda function shares the AMI to the Account B and also sends an email to the target account email recipients notifying them that the AMI has been shared.
  7. Log in to Account B and verify that the AMI has been shared.

Step 1: Deploy the AWS CloudFormation template

1. The CloudFormation template, template.yaml that deploys the solution can also found at this GitHub repository. Follow the instructions at the repository to deploy the stack.

Step 2: Verify your email address

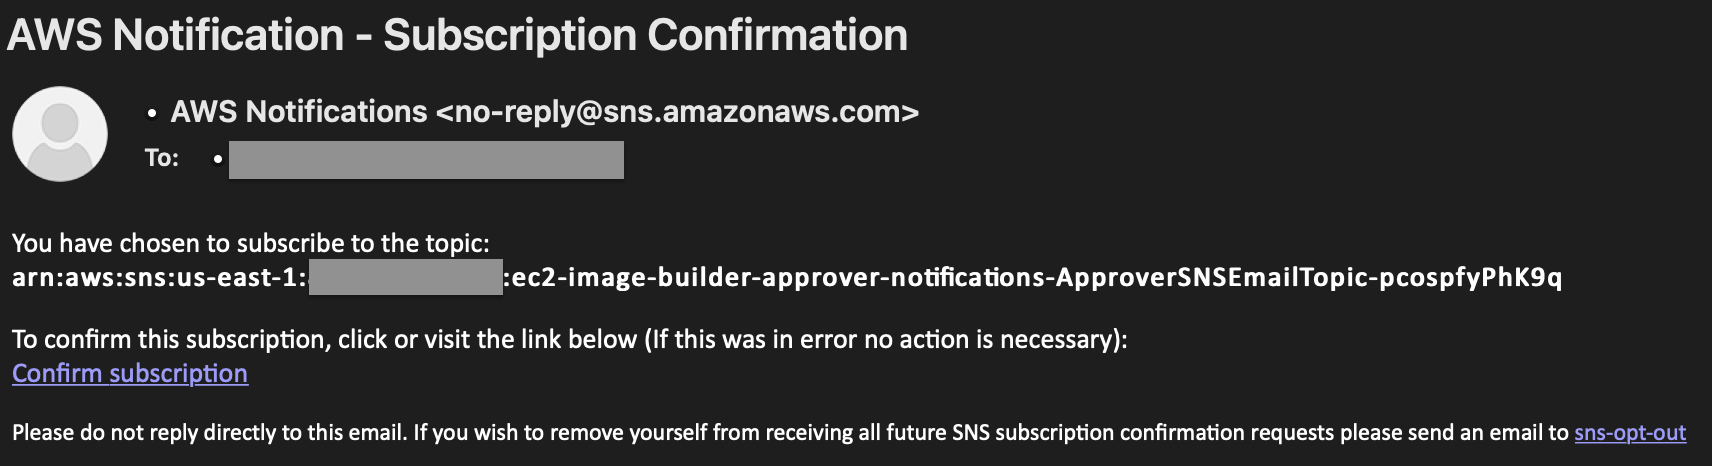
  1. After running the deployment, you will receive an email prompting you to confirm the Subscription at the approver email address. Choose Confirm subscription.

SNS Topic Subscription confirmation email

  1. This leads to the following screen, which shows that your subscription is confirmed.

subscription-confirmation

  1. Repeat the previous 2 steps for the target email address.

Step 3: Run the pipeline from the Image Builder console

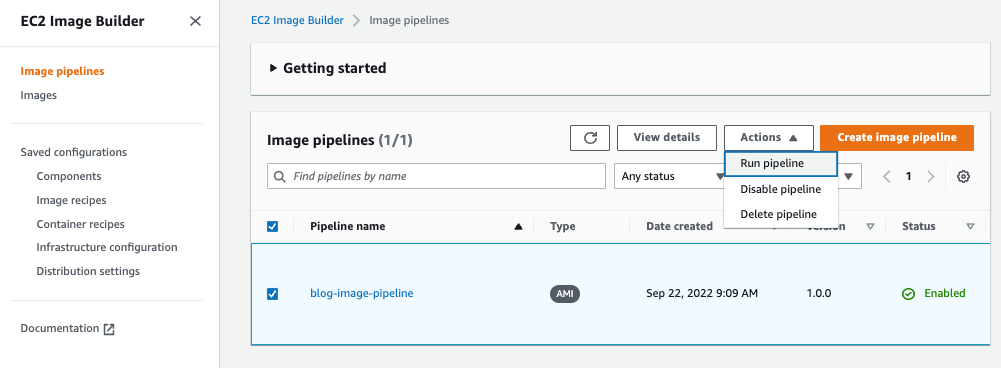
  1. In the Image Builder console, under Image pipelines, select the checkbox next to the Pipeline created, choose Actions, and select Run pipeline.

run-image-builder-pipeline

Note: The pipeline takes approximately 20 – 30 minutes to complete.

Step 4: [Optional] Launch an Amazon EC2 instance from the built AMI

If you have a requirement to manually validate the AMI before sharing it with other accounts or to the AWS organization an approver will launch an Amazon EC2 instance from the built AMI and conduct manual tests on the EC2 instance to make sure it is functional.

  1. In the Amazon EC2 console, under Images, choose AMIs. Validate that the AMI is created.

ami-in-account-a

  1. Follow AWS docs: Launching an EC2 instances from a custom AMI for steps on how to launch an Amazon EC2 instance from the AMI.

Step 5: Select the approval URL in the email sent

  1. When the pipeline is run successfully, you will receive another email with a URL to approve the AMI.

approval-email

  1. Before clicking on the Approve link, you must assume the IAM Role that is set as an approver for the Systems Manager step.
  2. In the CloudFormation console, choose the stack that was deployed.

cloudformation-stack

4. Choose Outputs and copy the IAM Role name.

ssm-approval-role-output

5. While logged in as the IAM Principal that has permissions to assume the approval IAM Role, follow the instructions at AWS IAM documentation for switching a role using the console to assume the approval role.
In the Switch Role page, in Role paste the name of the IAM Role that you copied in the previous step.

Note: This IAM Role was deployed with minimum permissions. Hence, seeing warning messages in the console is expected after assuming this role.

switch-role

6. Now in the approval email, select the Approve URL. This leads to the Systems Manager console. Choose Submit.

approve-console

7. After approving the manual step, the second step is executed, which shares the AMI to the target account.

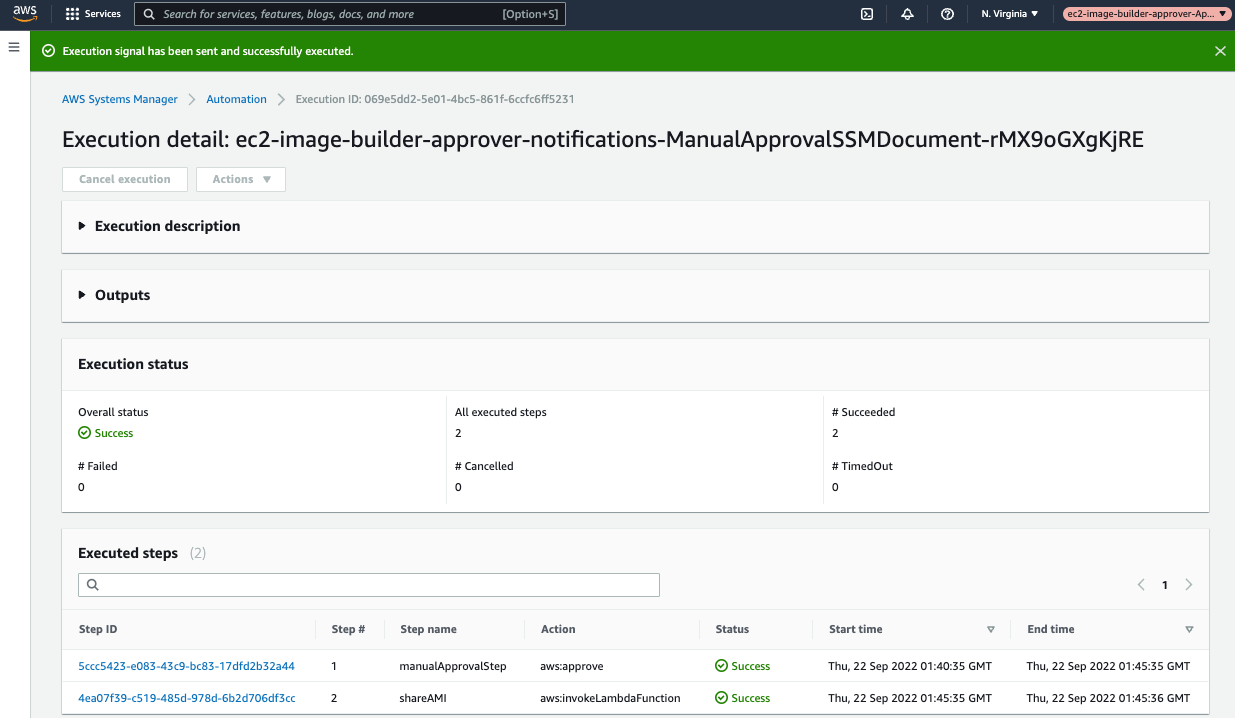
automation-step-success

Step 6: Verify that the AMI is shared to Account B

  1. Log in to Account B.
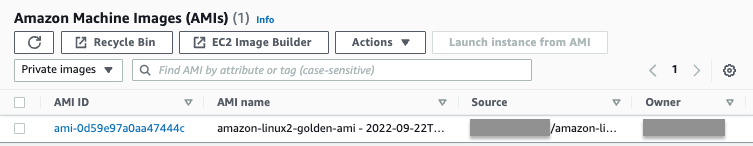
  2. In the Amazon EC2 console, under Images, choose AMIs. Then, in the dropdown, choose Private images. Validate that the AMI is shared.

verify-ami-in-account-b

  1. Verify that a success email notification was sent to the target account email address provided.

target-email

Clean up

This section provides the necessary information for deleting various resources created as part of this post.

  1. Deregister the AMIs that were created and shared.
    1. Log in to Account A and follow the steps at AWS documentation: Deregister your Linux AMI.
  2. Delete the CloudFormation stack. For instructions, refer to Deleting a stack on the AWS CloudFormation console.

Conclusion

In this post, we explained how to enable approval notifications for an Image Builder pipeline before AMIs are shared to other accounts. This solution can be extended to share to more than one AWS account or even to an AWS organization. With this solution, you will be notified when new golden images are created, allowing you to verify the accuracy of their configuration before sharing them to for wider use. This reduces the possibility of sharing AMIs with misconfigurations that the written tests may not have identified.

We invite you to experiment with different AMIs created using Image Builder, and with different Image Builder components. Check out this GitHub repository for various examples that use Image Builder. Also check out this blog on Image builder integrations with EC2 Auto Scaling Instance Refresh. Let us know your questions and findings in the comments, and have fun!

AWS Week in Review – October 10, 2022

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/aws/aws-week-in-review-october-10-2022/

This post is part of our Week in Review series. Check back each week for a quick roundup of interesting news and announcements from AWS!

I had an amazing start to the week last week as I was speaking at the AWS Community Day NL. This event had 500 attendees and over 70 speakers, and Dr. Werner Vogels, Amazon CTO, delivered the keynote. AWS Community Days are community-led conferences organized by local communities, with a variety of workshops and sessions. I recommend checking your region for any of these events.

Community Day NL

Last Week’s Launches
Here are some launches that got my attention during the previous week.

Amazon S3 Object Lambda now supports using your own code to change the results of HEAD and LIST requests, besides GET (which we launched last year). This feature now enables more capabilities for what you can do with S3 Object Lambda. Danilo made a Twitter thread with lots of use cases for this new launch.

Amazon SageMaker Clarify now can provide near real-time explanations for ML predictions. SageMaker Clarify is a service that provides explainability by ML models individual predictions. These explanations are important for developers to get visibility into their training data and models to identify potential bias.

AWS Storage Gateway now supports 15 TiB tapes. It increased the maximum supported virtual tape size on Tape Gateway from 5 TiB to 15 TiB, so you can store more data on a single virtual tape, and you can reduce the number of tapes you need to manage.

Amazon Aurora Serverless v2 now supports AWS CloudFormation. Early this year, we announced the general availability of Aurora Serverless v2, and now you can use AWS CloudFormation Templates to deploy and change the database along with the rest of your infrastructure.

AWS Config now supports 15 new resource types, including AWS DataSync, Amazon GuardDuty, Amazon Simple Email Service (Amazon SES), AWS AppSync, AWS Cloud Map, Amazon EC2, and AWS AppConfig. With this launch, you can use AWS Config to monitor configuration data for the supported resource types in your AWS account, and you can see how the configuration changes.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
Some other updates and news that you may have missed:

This week an article about how AWS is leading a pilot project to turn the Greek island of Naxos into a smart island caught my attention. The project introduces smart solutions for mobility, primary healthcare, and the transport of goods. The solution has been built based on four pillars that were important for the island: sustainability, telehealth, leisure, and digital skills. Check out the whole article to learn what they are doing.

Podcast Charlas Técnicas de AWS – If you understand Spanish, this podcast is for you. Podcast Charlas Técnicas is one of the official AWS podcasts in Spanish, and every other week there is a new episode. The podcast is meant for builders, and it shares stories about how customers implemented and learned AWS services, how to architect applications, and how to use new services. You can listen to all the episodes directly from your favorite podcast app or at AWS Podcasts en español.

AWS open-source news and updates – This is a newsletter curated by my colleague Ricardo to bring you the latest open-source projects, posts, events, and more.

Upcoming AWS Events
Check your calendars and sign up for these AWS events:

AWS re:Invent reserved seating opens on October 11. If you are planning to attend, book a spot in advance for your favorite sessions. AWS re:Invent is our biggest conference of the year, it happens in Las Vegas from November 28 to December 2, and registrations are open. Many writers of this blog have sessions at re:Invent, and you can search the event agenda using our names.

I started the post talking about AWS Community Days, and there is one in Warsaw, Poland, on October 14. If you are around Warsaw during this week, you can first check out the AWS Pop-up Hub in Warsaw that runs October 10-14 and then join for the Community Day.

On October 20, there is a virtual event for modernizing .NET workloads with Windows containers on AWS, You can register for free.

That’s all for this week. Check back next Monday for another Week in Review!

— Marcia

Use IAM Access Analyzer policy generation to grant fine-grained permissions for your AWS CloudFormation service roles

Post Syndicated from Joel Knight original https://aws.amazon.com/blogs/security/use-iam-access-analyzer-policy-generation-to-grant-fine-grained-permissions-for-your-aws-cloudformation-service-roles/

AWS Identity and Access Management (IAM) Access Analyzer provides tools to simplify permissions management by making it simpler for you to set, verify, and refine permissions. One such tool is IAM Access Analyzer policy generation, which creates fine-grained policies based on your AWS CloudTrail access activity—for example, the actions you use with Amazon Elastic Compute Cloud (Amazon EC2), AWS Lambda, and Amazon Simple Storage Service (Amazon S3). AWS has expanded policy generation capabilities to support the identification of actions used from over 140 services. New additions include services such as AWS CloudFormation, Amazon DynamoDB, and Amazon Simple Queue Service (Amazon SQS). When you request a policy, IAM Access Analyzer generates a policy by analyzing your CloudTrail logs to identify actions used from this group of over 140 services. The generated policy makes it efficient to grant only the required permissions for your workloads. For other services, Access Analyzer helps you by identifying the services used and guides you to add the necessary actions.

In this post, we will show how you can use Access Analyzer to generate an IAM permissions policy that restricts CloudFormation permissions to only those actions that are necessary to deploy a given template, in order to follow the principle of least privilege.

Permissions for AWS CloudFormation

AWS CloudFormation lets you create a collection of related AWS and third-party resources and provision them in a consistent and repeatable fashion. A common access management pattern is to grant developers permission to use CloudFormation to provision resources in the production environment and limit their ability to do so directly. This directs developers to make infrastructure changes in production through CloudFormation, using infrastructure-as-code patterns to manage the changes.

CloudFormation can create, update, and delete resources on the developer’s behalf by assuming an IAM role that has sufficient permissions. Cloud administrators often grant this IAM role broad permissions–in excess of what’s necessary to just create, update, and delete the resources from the developer’s template–because it’s not clear what the minimum permissions are for the template. As a result, the developer could use CloudFormation to create or modify resources outside of what’s required for their workload.

The best practice for CloudFormation is to acquire permissions by using the credentials from an IAM role you pass to CloudFormation. When you attach a least-privilege permissions policy to the role, the actions CloudFormation is allowed to perform can be scoped to only those that are necessary to manage the resources in the template. In this way, you can avoid anti-patterns such as assigning the AdministratorAccess or PowerUserAccess policies—both of which grant excessive permissions—to the role.

The following section will describe how to set up your account and grant these permissions.

Prepare your development account

Within your development account, you will configure the same method for deploying infrastructure as you use in production: passing a role to CloudFormation when you launch a stack. First, you will verify that you have the necessary permissions, and then you will create the role and the role’s permissions policy.

Get permissions to use CloudFormation and IAM Access Analyzer

You will need the following minimal permissions in your development account:

  • Permission to use CloudFormation, in particular to create, update, and delete stacks
  • Permission to pass an IAM role to CloudFormation
  • Permission to create IAM roles and policies
  • Permission to use Access Analyzer, specifically the GetGeneratedPolicy, ListPolicyGenerations, and StartPolicyGeneration actions

The following IAM permissions policy can be used to grant your identity these permissions.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "DeveloperPermissions”,
            "Effect": "Allow",
            "Action": [
                "access-analyzer:GetGeneratedPolicy",
                "access-analyzer:ListPolicyGenerations",
                "access-analyzer:StartPolicyGeneration",
                "cloudformation:*",
                "iam:AttachRolePolicy",
                "iam:CreatePolicy",
                "iam:CreatePolicyVersion",
                "iam:CreateRole",
                "iam:DeletePolicyVersion",
                "iam:DeleteRolePolicy",
                "iam:DetachRolePolicy",
                "iam:GetPolicy",
                "iam:GetPolicyVersion",
                "iam:GetRole",
                "iam:GetRolePolicy",
                "iam:ListPolicies",
                "iam:ListPolicyTags",
                "iam:ListPolicyVersions",
                "iam:ListRolePolicies",
                "iam:ListRoleTags",
                "iam:ListRoles",
                "iam:PutRolePolicy",
                "iam:UpdateAssumeRolePolicy"
            ],
            "Resource": "*"
        },
        {
            "Sid": "AllowPassCloudFormationRole”,
            "Effect": "Allow",
            "Action": [
                "iam:PassRole"
            ]
            "Resource": "*",
            "Condition": {
                "StringEquals": {
                    "iam:PassedToService": "cloudformation.amazonaws.com"
                }
            }
        }
    ]
}

Note: If your identity already has these permissions through existing permissions policies, there is no need to apply the preceding policy to your identity.

Create a role for CloudFormation

Creating a service role for CloudFormation in the development account makes it less challenging to generate the least-privilege policy, because it becomes simpler to identify the actions CloudFormation is taking as it creates and deletes resources defined in the template. By identifying the actions CloudFormation has taken, you can create a permissions policy to match.

To create an IAM role in your development account for CloudFormation

  1. Open the IAM console and choose Roles, then choose Create role.
  2. For the trusted entity, choose AWS service. From the list of services, choose CloudFormation.
  3. Choose Next: Permissions.
  4. Select one or more permissions policies that align with the types of resources your stack will create. For example, if your stack creates a Lambda function and an IAM role, choose the AWSLambda_FullAccess and IAMFullAccess policies.

    Note: Because you have not yet created the least-privilege permissions policy, the role is granted broader permissions than required. You will use this role to launch your stack and evaluate the resulting actions that CloudFormation takes, in order to build a lower-privilege policy.

  5. Choose Next: Tags to proceed.
  6. Enter one or more optional tags, and then choose Next: Review.
  7. Enter a name for the role, such as CloudFormationDevExecRole.
  8. Choose Create role.

Create and destroy the stack

To have CloudFormation exercise the actions required by the stack, you will need to create and destroy the stack.

To create and destroy the stack

  1. Navigate to CloudFormation in the console, expand the menu in the left-hand pane, and choose Stacks.
  2. On the Stacks page, choose Create Stack, and then choose With new resources.
  3. Choose Template is ready, choose Upload a template file, and then select the file for your template. Choose Next.
  4. Enter a Stack name, and then choose Next.
  5. For IAM execution role name, select the name of the role you created in the previous section (CloudFormationDevExecRole). Choose Next.
  6. Review the stack configuration. If present, select the check box(es) in the Capabilities section, and then choose Create stack.
  7. Wait for the stack to reach the CREATE_COMPLETE state before continuing.
  8. From the list of stacks, select the stack you just created, choose Delete, and then choose Delete stack.
  9. Wait until the stack reaches the DELETE_COMPLETE state (at which time it will also disappear from the list of active stacks).

Note: It’s recommended that you also modify the CloudFormation template and update the stack to initiate updates to the deployed resources. This will allow Access Analyzer to capture actions that update the stack’s resources, in addition to create and delete actions. You should also review the API documentation for the resources that are being used in your stack and identify any additional actions that may be required.

Now that the development environment is ready, you can create the least-privilege permissions policy for the CloudFormation role.

Use Access Analyzer to generate a fine-grained identity policy

Access Analyzer reviews the access history in AWS CloudTrail to identify the actions an IAM role has used. Because CloudTrail delivers logs within an average of about 15 minutes of an API call, you should wait at least that long after you delete the stack before you attempt to generate the policy, in order to properly capture all of the actions.

Note: CloudTrail must be enabled in your AWS account in order for policy generation to work. To learn how create a CloudTrail trail, see Creating a trail for your AWS account in the AWS CloudTrail User Guide.

To generate a permissions policy by using Access Analyzer

  1. Open the IAM console and choose Roles. In the search box, enter CloudFormationDevExecRole and select the role name in the list.
  2. On the Permissions tab, scroll down and choose Generate policy based on CloudTrail events to expand this section. Choose Generate policy.
  3. Select the time period of the CloudTrail logs you want analyzed.
  4. Select the AWS Region where you created and deleted the stack, and then select the CloudTrail trail name in the drop-down list.
  5. If this is your first time generating a policy, choose Create and use a new service role to have an IAM role automatically created for you. You can view the permissions policy the role will receive by choosing View permission details. Otherwise, choose Use an existing service role and select a role in the drop-down list.

    The policy generation options are shown in Figure 1.

    Figure 1: Policy generation options

    Figure 1: Policy generation options

  6. Choose Generate policy.

You will be redirected back to the page that shows the CloudFormationDevExecRole role. The Status in the Generate policy based on CloudTrail events section will show In progress. Wait for the policy to be generated, at which time the status will change to Success.

Review the generated policy

You must review and save the generated policy before it can be applied to the role.

To review the generated policy

  1. While you are still viewing the CloudFormationDevExecRole role in the IAM console, under Generate policy based on CloudTrail events, choose View generated policy.
  2. The Generated policy page will open. The Actions included in the generated policy section will show a list of services and one or more actions that were found in the CloudTrail log. Review the list for omissions. Refer to the IAM documentation for a list of AWS services for which an action-level policy can be generated. An example list of services and actions for a CloudFormation template that creates a Lambda function is shown in Figure 2.
    Figure 2: Actions included in the generated policy

    Figure 2: Actions included in the generated policy

  3. Use the drop-down menus in the Add actions for services used section to add any necessary additional actions to the policy for the services that were identified by using CloudTrail. This might be needed if an action isn’t recorded in CloudTrail or if action-level information isn’t supported for a service.

    Note: The iam:PassRole action will not show up in CloudTrail and should be added manually if your CloudFormation template assigns an IAM role to a service (for example, when creating a Lambda function). A good rule of thumb is: If you see iam:CreateRole in the actions, you likely need to also allow iam:PassRole. An example of this is shown in Figure 3.

    Figure 3: Adding PassRole as an IAM action

    Figure 3: Adding PassRole as an IAM action

  4. When you’ve finished adding additional actions, choose Next.

Generated policies contain placeholders that need to be filled in with resource names, AWS Region names, and other variable data. The actual values for these placeholders should be determined based on the content of your CloudFormation template and the Region or Regions you plan to deploy the template to.

To replace placeholders with real values

  • In the generated policy, identify each of the Resource properties that use placeholders in the value, such as ${RoleNameWithPath} or ${Region}. Use your knowledge of the resources that your CloudFormation template creates to properly fill these in with real values.
    • ${RoleNameWithPath} is an example of a placeholder that reflects the name of a resource from your CloudFormation template. Replace the placeholder with the actual name of the resource.
    • ${Region} is an example of a placeholder that reflects where the resource is being deployed, which in this case is the AWS Region. Replace this with either the Region name (for example, us-east-1), or a wildcard character (*), depending on whether you want to restrict the policy to a specific Region or to all Regions, respectively.

For example, a statement from the policy generated earlier is shown following.

{
    "Effect": "Allow",
    "Action": [
        "lambda:CreateFunction",
        "lambda:DeleteFunction",
        "lambda:GetFunction",
        "lambda:GetFunctionCodeSigningConfig"
    ],
    "Resource": "arn:aws:lambda:${Region}:${Account}:function:${FunctionName}"
},

After substituting real values for the placeholders in Resource, it looks like the following.

{
    "Effect": "Allow",
    "Action": [
        "lambda:CreateFunction",
        "lambda:DeleteFunction",
        "lambda:GetFunction",
        "lambda:GetFunctionCodeSigningConfig"
    ],
    "Resource": "arn:aws:lambda:*:123456789012:function:MyLambdaFunction"
},

This statement allows the Lambda actions to be performed on a function named MyLambdaFunction in AWS account 123456789012 in any Region (*). Substitute the correct values for Region, Account, and FunctionName in your policy.

The IAM policy editor window will automatically identify security or other issues in the generated policy. Review and remediate the issues identified in the Security, Errors, Warnings, and Suggestions tabs across the bottom of the window.

To review and remediate policy issues

  1. Use the Errors tab at the bottom of the IAM policy editor window (powered by IAM Access Analyzer policy validation) to help identify any placeholders that still need to be replaced. Access Analyzer policy validation reviews the policy and provides findings that include security warnings, errors, general warnings, and suggestions for your policy. To find more information about the different checks, see Access Analyzer policy validation. An example of policy errors caused by placeholders still being present in the policy is shown in Figure 4.
    Figure 4: Errors identified in the generated policy

    Figure 4: Errors identified in the generated policy

  2. Use the Security tab at the bottom of the editor window to review any security warnings, such as passing a wildcard (*) resource with the iam:PassRole permission. Choose the Learn more link beside each warning for information about remediation. An example of a security warning related to PassRole is shown in Figure 5.
    Figure 5: Security warnings identified in the generated policy

    Figure 5: Security warnings identified in the generated policy

Remediate the PassRole With Star In Resource warning by modifying Resource in the iam:PassRole statement to list the Amazon Resource Name (ARN) of any roles that CloudFormation needs to pass to other services. Additionally, add a condition to restrict which service the role can be passed to. For example, to allow passing a role named MyLambdaRole to the Lambda service, the statement would look like the following.

        {
            "Effect": "Allow",
            "Action": [
                "iam:PassRole"
            ],
            "Resource": [
                "arn:aws:iam::123456789012:role/MyLambdaRole"
            ],
            "Condition": {
                "StringEquals": {
                    "iam:PassedToService": [
                        "lambda.amazonaws.com"
                    ]
                }
            }
        }

The generated policy can now be saved as an IAM policy.

To save the generated policy

  1. In the IAM policy editor window, choose Next.
  2. Enter a name for the policy and an optional description.
  3. Review the Summary section with the list of permissions in the policy.
  4. Enter optional tags in the Tags section.
  5. Choose Create and attach policy.

Test this policy by replacing the existing role policy with this newly generated policy. Then create and destroy the stack again so that the necessary permissions are granted. If the stack fails during creation or deletion, follow the steps to generate the policy again and make sure that the correct values are being used for any iam:PassRole statements.

Deploy the CloudFormation role and policy

Now that you have the least-privilege policy created, you can give this policy to the cloud administrator so that they can deploy the policy and CloudFormation service role into production.

To create a CloudFormation template that the cloud administrator can use

  1. Open the IAM console, choose Policies, and then use the search box to search for the policy you created. Select the policy name in the list.
  2. On the Permissions tab, make sure that the {}JSON button is activated. Select the policy document by highlighting from line 1 all the way to the last line in the policy, as shown in Figure 6.
    Figure 6: Highlighting the generated policy

    Figure 6: Highlighting the generated policy

  3. With the policy still highlighted, use your keyboard to copy the policy into the clipboard (Ctrl-C on Linux or Windows, Option-C on macOS).
  4. Paste the permissions policy JSON object into the following CloudFormation template, replacing the <POLICY-JSON-GOES-HERE> marker. Be sure to indent the left-most curly braces of the JSON object so that they are to the right of the PolicyDocument keyword.
    AWSTemplateFormatVersion: '2010-09-09'
    
    Parameters:
      PolicyName:
        Type: String
        Description: The name of the IAM policy that will be created
    
      RoleName:
        Type: String
        Description: The name of the IAM role that will be created
    
    Resources:
      CfnPolicy:
        Type: AWS::IAM::ManagedPolicy
        Properties:
          ManagedPolicyName: !Ref PolicyName
          Path: /
          PolicyDocument: >
            <POLICY-JSON-GOES-HERE>
    
      CfnRole:
        Type: AWS::IAM::Role
        Properties:
          RoleName: !Ref RoleName
          AssumeRolePolicyDocument:
            Version: '2012-10-17'
            Statement:
              - Action:
                - sts:AssumeRole
                Effect: Allow
                Principal:
                  Service:
                    - cloudformation.amazonaws.com
          ManagedPolicyArns:
            - !Ref CfnPolicy
          Path: /

    For example, after pasting the policy, the CfnPolicy resource in the template will look like the following.

    CfnPolicy:
        Type: AWS::IAM::ManagedPolicy
        Properties:
          ManagedPolicyName: !Ref PolicyName
          Path: /
          PolicyDocument: >
            {
                "Version": "2012-10-17",
                "Statement": [
                    {
                        "Effect": "Allow",
                        "Action": "ec2:DescribeNetworkInterfaces",
                        "Resource": [
                            "*"
                        ]
                    },
                    {
                        "Effect": "Allow",
                        "Action": [
                            "iam:AttachRolePolicy",
                            "iam:CreateRole",
                            "iam:DeleteRole",
                            "iam:DetachRolePolicy",
                            "iam:GetRole"
                        ],
                        "Resource": [
                            "arn:aws:iam::123456789012:role/MyLambdaRole"
                        ]
                    },
                    {
                        "Effect": "Allow",
                        "Action": [
                            "lambda:CreateFunction",
                            "lambda:DeleteFunction",
                            "lambda:GetFunction",
                            "lambda:GetFunctionCodeSigningConfig"
                        ],
                        "Resource": [
                            "arn:aws:lambda:*:123456789012:function:MyLambdaFunction"
                        ]
                    },
                    {
                        "Effect": "Allow",
                        "Action": [
                            "iam:PassRole"
                        ],
                        "Resource": [
                            "arn:aws:iam::123456789012:role/MyLambdaRole"
                        ],
                        "Condition": {
                            "StringEquals": {
                                "iam:PassedToService": [
                                    "lambda.amazonaws.com"
                                ]
                            }
                        }
                    }
                ]
            }

  5. Save the CloudFormation template and share it with the cloud administrator. They can use this template to create an IAM role and permissions policy that CloudFormation can use to deploy resources in the production account.

Note: Verify that in addition to having the necessary permissions to work with CloudFormation, your production identity also has permission to perform the iam:PassRole action with CloudFormation for the role that the preceding template creates.

As you continue to develop your stack, you will need to repeat the steps in the Use Access Analyzer to create a permissions policy and Deploy the CloudFormation role and policy sections of this post in order to make sure that the permissions policy remains up-to-date with the permissions required to deploy your stack.

Considerations

If your CloudFormation template uses custom resources that are backed by AWS Lambda, you should also run Access Analyzer on the IAM role that is created for the Lambda function in order to build an appropriate permissions policy for that role.

To generate a permissions policy for a Lambda service role

  1. Launch the stack in your development AWS account to create the Lamba function’s role.
  2. Make a note of the name of the role that was created.
  3. Destroy the stack in your development AWS account.
  4. Follow the instructions from the Use Access Analyzer to generate a fine-grained identity policy and Review the generated policy sections of this post to create the least-privilege policy for the role, substituting the Lambda function’s role name for CloudFormationDevExecRole.
  5. Build the resulting least-privilege policy into the CloudFormation template as the Lambda function’s permission policy.

Conclusion

IAM Access Analyzer helps generate fine-grained identity policies that you can use to grant CloudFormation the permissions it needs to create, update, and delete resources in your stack. By granting CloudFormation only the necessary permissions, you can incorporate the principle of least privilege, developers can deploy their stacks in production using reduced permissions, and cloud administrators can create guardrails for developers in production settings.

For additional information on applying the principle of least privilege to AWS CloudFormation, see How to implement the principle of least privilege with CloudFormation StackSets.

If you have feedback about this blog post, submit comments in the Comments section below. You can also start a new thread on AWS Identity and Access Management re:Post to get answers from the community.

Want more AWS Security news? Follow us on Twitter.

Author

Joel Knight

Joel is a Senior Consultant, Infrastructure Architecture, with AWS and is based in Calgary, Canada. When not wrangling infrastructure-as-code templates, Joel likes to spend time with his family and dabble in home automation.

Mathangi Ramesh

Mathangi Ramesh

Mathangi is the product manager for AWS Identity and Access Management. She enjoys talking to customers and working with data to solve problems. Outside of work, Mathangi is a fitness enthusiast and a Bharatanatyam dancer. She holds an MBA degree from Carnegie Mellon University.

IAM Access Analyzer makes it simpler to author and validate role trust policies

Post Syndicated from Mathangi Ramesh original https://aws.amazon.com/blogs/security/iam-access-analyzer-makes-it-simpler-to-author-and-validate-role-trust-policies/

AWS Identity and Access Management (IAM) Access Analyzer provides many tools to help you set, verify, and refine permissions. One part of IAM Access Analyzer—policy validation—helps you author secure and functional policies that grant the intended permissions. Now, I’m excited to announce that AWS has updated the IAM console experience for role trust policies to make it simpler for you to author and validate the policy that controls who can assume a role. In this post, I’ll describe the new capabilities and show you how to use them as you author a role trust policy in the IAM console.

Overview of changes

A role trust policy is a JSON policy document in which you define the principals that you trust to assume the role. The principals that you can specify in the trust policy include users, roles, accounts, and services. The new IAM console experience provides the following features to help you set the right permissions in the trust policy:

  • An interactive policy editor prompts you to add the right policy elements, such as the principal and the allowed actions, and offers context-specific documentation.
  • As you author the policy, IAM Access Analyzer runs over 100 checks against your policy and highlights issues to fix. This includes new policy checks specific to role trust policies, such as a check to make sure that you’ve formatted your identity provider correctly. These new checks are also available through the IAM Access Analyzer policy validation API.
  • Before saving the policy, you can preview findings for the external access granted by your trust policy. This helps you review external access, such as access granted to a federated identity provider, and confirm that you grant only the intended access when you create the policy. This functionality was previously available through the APIs, but now it’s also available in the IAM console.

In the following sections, I’ll walk you through how to use these new features.

Example scenario

For the walkthrough, consider the following example, which is illustrated in Figure 1. You are a developer for Example Corp., and you are working on a web application. You want to grant the application hosted in one account—the ApplicationHost account—access to data in another account—the BusinessData account. To do this, you can use an IAM role in the BusinessData account to grant temporary access to the application through a role trust policy. You will grant a role in the ApplicationHost account—the PaymentApplication role—to access the BusinessData account through a role—the ApplicationAccess role. In this example, you create the ApplicationAccess role and grant cross-account permissions through the trust policy by using the new IAM console experience that helps you set the right permissions.

Figure 1: Visual explanation of the scenario

Figure 1: Visual explanation of the scenario

Create the role and grant permissions through a role trust policy with the policy editor

In this section, I will show you how to create a role trust policy for the ApplicationAccess role to grant the application access to the data in your account through the policy editor in the IAM console.

To create a role and grant access

  1. In the BusinessData account, open the IAM console, and in the left navigation pane, choose Roles.
  2. Choose Create role, and then select Custom trust policy, as shown in Figure 2.
    Figure 2: Select "Custom trust policy" when creating a role

    Figure 2: Select “Custom trust policy” when creating a role

  3. In the Custom trust policy section, for 1. Add actions for STS, select the actions that you need for your policy. For example, to add the action sts:AssumeRole, choose AssumeRole.
    Figure 3: JSON role trust policy

    Figure 3: JSON role trust policy

  4. For 2. Add a principal, choose Add to add a principal.
  5. In the Add principal box, for Principal type, select IAM roles. This populates the ARN field with the format of the role ARN that you need to add to the policy, as shown in Figure 4.
    Figure 4: Add a principal to your role trust policy

    Figure 4: Add a principal to your role trust policy

  6. Update the role ARN template with the actual account and role information, and then choose Add principal. In our example, the account is ApplicationHost with an AWS account number of 111122223333, and the role is PaymentApplication role. Therefore, the role ARN is arn:aws:iam:: 111122223333: role/PaymentApplication. Figure 5 shows the role trust policy with the action and principal added.
    Figure 5: Sample role trust policy

    Figure 5: Sample role trust policy

  7. (Optional) To add a condition, for 3. Add a condition, choose Add, and then complete the Add condition box according to your needs.

Author secure policies by reviewing policy validation findings

As you author the policy, you can see errors or warnings related to your policy in the policy validation window, which is located below the policy editor in the console. With this launch, policy validation in IAM Access Analyzer includes 13 new checks focused on the trust relationship for the role. The following are a few examples of these checks and how to address them:

  • Role trust policy unsupported wildcard in principal – you can’t use a * in your role trust policy.
  • Invalid federated principal syntax in role trust policy – you need to fix the format of the identity provider.
  • Missing action for condition key – you need to add the right action for a given condition, such as the sts:TagSession when there are session tag conditions.

For a complete list of checks, see Access Analyzer policy check reference.

To review and fix policy validation findings

  1. In the policy validation window, do the following:
    • Choose the Security tab to check if your policy is overly permissive.
    • Choose the Errors tab to review any errors associated with the policy.
    • Choose the Warnings tab to review if aspects of the policy don’t align with AWS best practices.
    • Choose the Suggestions tab to get recommendations on how to improve the quality of your policy.
    Figure 6: Policy validation window in IAM Access Analyzer with a finding for your policy

    Figure 6: Policy validation window in IAM Access Analyzer with a finding for your policy

  2. For each finding, choose Learn more to review the documentation associated with the finding and take steps to fix it. For example, Figure 6 shows the error Mismatched Action For Principal. To fix the error, remove the action sts:AssumeRoleWithWebIdentity.

Preview external access by reviewing cross-account access findings

IAM Access Analyzer also generates findings to help you assess if a policy grants access to external entities. You can review the findings before you create the policy to make sure that the policy grants only intended access. To preview the findings, you create an analyzer and then review the findings.

To preview findings for external access

  1. Below the policy editor, in the Preview external access section, choose Go to Access Analyzer, as shown in Figure 7.

    Note: IAM Access Analyzer is a regional service, and you can create a new analyzer in each AWS Region where you operate. In this situation, IAM Access Analyzer looks for an analyzer in the Region where you landed on the IAM console. If IAM Access Analyzer doesn’t find an analyzer there, it asks you to create an analyzer.

    Figure 7: Preview external access widget without an analyzer

    Figure 7: Preview external access widget without an analyzer

  2. On the Create analyzer page, do the following to create an analyzer:
    • For Name, enter a name for your analyzer.
    • For Zone of trust, select the correct account.
    • Choose Create analyzer.
    Figure 8: Create an analyzer to preview findings

    Figure 8: Create an analyzer to preview findings

  3. After you create the analyzer, navigate back to the role trust policy for your role to review the external access granted by this policy. The following figure shows that external access is granted to PaymentApplication.
    Figure 9: Preview finding

    Figure 9: Preview finding

  4. If the access is intended, you don’t need to take any action. In this example, I want the PaymentApplication role in the ApplicationHost account to assume the role that I’m creating.
  5. If the access is unintended, resolve the finding by updating the role ARN information.
  6. Select Next and grant the required IAM permissions for the role.
  7. Name the role ApplicationAccess, and then choose Save to save the role.

Now the application can use this role to access the BusinessData account.

Conclusion

By using the new IAM console experience for role trust policies, you can confidently author policies that grant the intended access. IAM Access Analyzer helps you in your least-privilege journey by evaluating the policy for potential issues to make it simpler for you to author secure policies. IAM Access Analyzer also helps you preview external access granted through the trust policy to help ensure that the granted access is intended. To learn more about how to preview IAM Access Analyzer cross-account findings, see Preview access in the documentation. To learn more about IAM Access Analyzer policy validation checks, see Access Analyzer policy validation. These features are also available through APIs.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread at AWS IAM re:Post or contact AWS Support.

Mathangi Ramesh

Mathangi Ramesh

Mathangi is the product manager for AWS Identity and Access Management. She enjoys talking to customers and working with data to solve problems. Outside of work, Mathangi is a fitness enthusiast and a Bharatanatyam dancer. She holds an MBA degree from Carnegie Mellon University.

AWS Week in Review – October 3, 2022

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/aws-week-in-review-october-3-2022/

This post is part of our Week in Review series. Check back each week for a quick roundup of interesting news and announcements from AWS!

A new week and a new month just started. Curious which were the most significant AWS news from the previous seven days? I got you covered with this post.

Last Week’s Launches
Here are the launches that got my attention last week:

Amazon File Cache – A high performance cache on AWS that accelerates and simplifies demanding cloud bursting and hybrid workflows by giving access to files using a fast and familiar POSIX interface, no matter if the original files live on premises on any file system that can be accessed through NFS v3 or on S3.

Amazon Data Lifecycle Manager – You can now automatically archive Amazon EBS snapshots to save up to 75 percent on storage costs for those EBS snapshots that you intend to retain for more than 90 days and rarely access.

AWS App Runner – You can now build and run web applications and APIs from source code using the new Node.js 16 managed runtime.

AWS Copilot – The CLI for containerized apps adds IAM permission boundaries, support for FIFO SNS/SQS for the Copilot worker-service pattern, and using Amazon CloudFront for low-latency content delivery and fast TLS-termination for public load-balanced web services.

Bottlerocket – The Linux-based operating system purpose-built to run container workloads is now supported by Amazon Inspector. Amazon Inspector can now recommend an update of Bottlerocket if it finds a vulnerability.

Amazon SageMaker Canvas – Now supports mathematical functions and operators for richer data exploration and to understand the relationships between variables in your data.

AWS Compute Optimizer – Now provides cost and performance optimization recommendations for 37 new EC2 instance types, including bare metal instances (m6g.metal) and compute optimized instances (c7g.2xlarge, hpc6a.48xlarge), and new memory metrics for Windows instances.

AWS Budgets – Use a simplified 1-click workflow for common budgeting scenarios with step-by-step tutorials on how to use each template.

Amazon Connect – Now provides an updated flow designer UI that makes it easier and faster to build personalized and automated end-customer experiences, as well as a queue dashboard to view and compare real-time queue performance through time series graphs.

Amazon WorkSpaces – You can now provision Ubuntu desktops and use virtual desktops for new categories of workloads, such as for your developers, engineers, and data scientists.

Amazon WorkSpaces Core – A fully managed infrastructure-only solution for third-party Virtual Desktop Infrastructure (VDI) management software that simplifies VDI migration and combines your current VDI software with the security and reliability of AWS. Read more about it in this Desktop and Application Streaming blog post.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
A few more blog posts you might have missed:

Introducing new language extensions in AWS CloudFormation – In this Cloud Operations & Migrations blog post, we introduce the new language transform that enhances CloudFormation core language with intrinsic functions that simplify handling JSON strings (Fn::ToJsonString), array lengths (Fn::Length), and update and deletion policies.

Building a GraphQL API with Java and AWS Lambda – This blog shows different options for resolving GraphQL queries using serverless technologies on AWS.

For AWS open-source news and updates, here’s the latest newsletter curated by Ricardo to bring you the most recent updates on open-source projects, posts, events, and more.

Upcoming AWS Events
As usual, there are many opportunities to meet:

AWS Summits– Connect, collaborate, and learn about AWS at these free in-person events: Bogotá (October 4), and Singapore (October 6).

AWS Community Days – AWS Community Day events are community-led conferences to share and learn together. Join us in Amersfoort, Netherlands (on October 3, today), Warsaw, Poland (October 14), and Dresden, Germany (October 19).

That’s all from me for this week. Come back next Monday for another Week in Review!

— Danilo

Amazon Personalize customer outreach on your ecommerce platform

Post Syndicated from Sridhar Chevendra original https://aws.amazon.com/blogs/architecture/amazon-personalize-customer-outreach-on-your-ecommerce-platform/

In the past, brick-and-mortar retailers leveraged native marketing and advertisement channels to engage with consumers. They have promoted their products and services through TV commercials, and magazine and newspaper ads. Many of them have started using social media and digital advertisements. Although marketing approaches are beginning to modernize and expand to digital channels, businesses still depend on expensive marketing agencies and inefficient manual processes to measure campaign effectiveness and understand buyer behavior. The recent pandemic has forced many retailers to take their businesses online. Those who are ready to embrace these changes have embarked on a technological and digital transformation to connect to their customers. As a result, they have begun to see greater business success compared to their peers.

Digitizing a business can be a daunting task, due to lack of expertise and high infrastructure costs. By using Amazon Web Services (AWS), retailers are able to quickly deploy their products and services online with minimal overhead. They don’t have to manage their own infrastructure. With AWS, retailers have no upfront costs, have minimal operational overhead, and have access to enterprise-level capabilities that scale elastically, based on their customers’ demands. Retailers can gain a greater understanding of customers’ shopping behaviors and personal preferences. Then, they are able to conduct effective marketing and advertisement campaigns, and develop and measure customer outreach. This results in increased satisfaction, higher retention, and greater customer loyalty. With AWS you can manage your supply chain and directly influence your bottom line.

Building a personalized shopping experience

Let’s dive into the components involved in building this experience. The first step in a retailer’s digital transformation journey is to create an ecommerce platform for their customers. This platform enables the organization to capture their customers’ actions, also referred to as ‘events’. Some examples of events are clicking on the shopping site to browse product categories, searching for a particular product, adding an item to the shopping cart, and purchasing a product. Each of these events gives the organization information about their customer’s intent, which is invaluable in creating a personalized experience for that customer. For instance, if a customer is browsing the “baby products” category, it indicates their interest in that category even if a purchase is not made. These insights are typically difficult to capture in an in-store experience. Online shopping makes gaining this knowledge much more straightforward and scalable.

The proposed solution outlines the use of AWS services to create a digital experience for a retailer and consumers. The three key areas are: 1) capturing customer interactions, 2) making real-time recommendations using AWS managed Artificial Intelligence/Machine Learning (AI/ML) services, and 3) creating an analytics platform to detect patterns and adjust customer outreach campaigns. Figure 1 illustrates the solution architecture.

Digital shopping experience architecture

Figure 1. Digital shopping experience architecture

For this use case, let’s assume that you are the owner of a local pizzeria, and you manage deliveries through an ecommerce platform like Shopify or WooCommerce. We will walk you through how to best serve your customer with a personalized experience based on their preferences.

The proposed solution consists of the following components:

  1. Data collection
  2. Promotion campaigns
  3. Recommendation engine
  4. Data analytics
  5. Customer reachability

Let’s explore each of these components separately.

Data collection with Amazon Kinesis Data Streams

When a customer uses your web/mobile application to order a pizza, the application captures their activity as click-stream ‘events’. These events provide valuable insights about your customers’ behavior. You can use these insights to understand the trends and browsing pattern of prospects who visited your web/mobile app, and use the data collected for creating promotion campaigns. As your business scales, you’ll need a durable system to preserve these events against system failures, and scale based on unpredictable traffic on your platform.

Amazon Kinesis is a Multi-AZ, managed streaming service that provides resiliency, scalability, and durability to capture an unlimited number of events without any additional operational overhead. Using Kinesis producers (Kinesis Agent, Kinesis Producer Library, and the Kinesis API), you can configure applications to capture your customer activity. You can ingest these events from the frontend, and then publish them to Amazon Kinesis Data Streams.

Let us start by setting up Amazon Kinesis Data Streams to capture the real-time sales transactions from the online channels like a portal or mobile app. For this blog post, we have used the Kaggle’s public data set as a reference. Figure 2 illustrates a snapshot of sample data to build personalized recommendations for a customer.

Sample sales transaction data

Figure 2. Sample sales transaction data

Promotion campaigns with AWS Lambda

One way to increase customer conversion is by offering discounts. When the customer adds a pizza to their cart, you want to make sure they are receiving the best deal. Let’s assume that by adding an additional item, your customer will receive the best possible discount. Just by knowing the total cost of added items to the cart, you can provide these relevant promotions to this customer.

For this scenario, the AWS Lambda service polls the Amazon Kinesis Data Streams to read all the events in the stream. It then matches the events based on your criteria of items in the cart. In turn, these events will be processed by the Lambda function. The Lambda function will read your up-to-date promotions stored in Amazon DynamoDB. As an option, caching recent or most popular promotions will improve your application response time, as well as improve the customer experience on your platform. Amazon DynamoDB DAX is an integrated caching for DynamoDB that caches the most recent or popular promotions or items.

For example, when the customer added the items to their shopping cart, Lambda will send promotion details to them based on the purchase amount. This can be for free shipping or discount of a certain percentage. Figure 3 illustrates the snapshot of sample promotions.

Promotions table in DynamoDB

Figure 3. Promotions table in DynamoDB

Recommendations engine with Amazon Personalize

In addition to sharing these promotions with your customer, you may also want to share the recommended add-ons. In order to understand your customer preferences, you must gather historical datasets to determine patterns and generate relevant recommendations. Since web activity consists of millions of events, this would be a daunting task for humans to review, determine the patterns, and make recommendations. And since user preferences change, you need a system that can use all this volume of data and provide accurate predictions.

Amazon Personalize is a managed AI/ML service that will help you to train an ML model based on datasets. It provides an inference point for real-time recommendations prior to having ML experience. Based on the datasets, Amazon Personalize also provides recipes to generate recommendations. As your customers interact on the ecommerce platform, your frontend application calls Amazon Personalize inference endpoints. It then retrieves a set of personalized recommendations based on your customer preferences.

Here is the sample Python code to display the list of available recommenders, and associated recommendations.

import boto3
import json
client = boto3.client('personalize')

# Connect to the personalize runtime for the customer recommendations

recomm_endpoint = boto3.client('personalize-runtime')
response = recomm_endpoint.get_recommendations(itemId='79323P',
  recommenderArn='arn:aws:personalize:us-east-1::recommender/my-items',
  numResults=5)

print(json.dumps(response['itemList'], indent=2))

[
  {
    "itemId": "79323W"
  },
  {
    "itemId": "79323GR"
  },
  {
    "itemId": "79323LP"
  },
  {
  "itemId": "79323B"
  },
  {
    "itemId": "79323G"
  }
]

You can use Amazon Kinesis Data Firehose to read the data near real time from the Amazon Kinesis Data Streams collected the data from the front-end applications. Then you can store this data in Amazon Simple Storage Service (S3). Amazon S3 is peta-byte scale storage help you scale and acts as a repository and single source of truth. We use S3 data as seed data to build a personalized recommendation engine using Amazon Personalize. As your customers interact on the ecommerce platform, call the Amazon Personalize inference endpoint to make personalized recommendations based on user preferences.

Customer reachability with Amazon Pinpoint

If a customer adds products to their cart but never checks out, you may want to send them a reminder. You can set up an email to suggest they re-order after a period of time after their first order. Or you may want to send them promotions based on their preferences. And as your customers’ behavior changes, you probably want to adapt your messaging accordingly.

Your customer may have a communication preference, such as phone, email, SMS, or in-app notifications. If an order has an issue, you can inform the customer as soon as possible using their preferred method of communication, and perhaps follow it up with a discount.

Amazon Pinpoint is a flexible and scalable outbound and inbound marketing communications service. You can add users to Audience Segments, create reusable content templates integrated with Amazon Personalize, and run scheduled campaigns. With Amazon Pinpoint journeys, you can send action or time-based notifications to your users.

The following workflow shown in Figure 4, illustrates customer communication workflow for promotion. A journey is created for a cohort of college students: a “Free Drink” promotion is offered with a new order. You can send this promotion over email. If the student opens the email, you can immediately send them a push notification reminding them to place an order. But if they didn’t open this email, you could wait three days, and follow up with a text message.

Promotion workflow in Amazon Pinpoint

Figure 4. Promotion workflow in Amazon Pinpoint

Data analytics with Amazon Athena and Amazon QuickSight

To understand the effectiveness of your campaigns, you can use S3 data as a source for Amazon Athena. Athena is an interactive query service that analyzes data in Amazon S3 using standard SQL. Athena is serverless, so there is no infrastructure to manage, and you pay only for the queries that you run.

There are different ways to create visualizations in Amazon QuickSight. For instance, you can use Amazon S3 as a data lake. One option is to import your data into SPICE (Super-fast, Parallel, In-memory Calculation Engine) to provide high performance and concurrency. You can also create a direct connection to the underlying data source. For this use case, we choose to import to SPICE, which provides faster visualization in a production setup. Schedule consistent refreshes to help ensure that dashboards are referring to the most current data.

Once your data is imported to your SPICE, review QuickSight’s visualization dashboard. Here, you’ll be able to choose from a wide variety of charts and tables, while adding interactive features like drill downs and filters.

The process following illustrates how to create a customer outreach strategy using ZIP codes, and allocate budgets to the marketing campaigns accordingly. First, we use this sample SQL command that we ran in Athena to query for top 10 pizza providers. The results are shown in Figure 5.

SELECT name, count(*) as total_count FROM "analyticsdemodb"."fooddatauswest2"
group by name
order by total_count desc
limit 10

Athena query results for top 10 pizza providers

Figure 5. Athena query results for top 10 pizza providers

Second, here is the sample SQL command that we ran in Athena to find Total pizza counts by postal code (ZIP code). Figure 6 shows a visualization to help create customer outreach strategy per ZIP codes and budget the marketing campaigns accordingly.

SELECT postalcode, count(*) as total_count FROM "analyticsdemodb"."fooddatauswest2"
where postalcode is not null
group by postalcode
order by total_count desc limit 50;

QuickSight visualization showing pizza orders by zip codes

Figure 6. QuickSight visualization showing pizza orders by zip codes

Conclusion

AWS enables you to build an ecommerce platform and scale your existing business with minimal operational overhead and no upfront costs. You can augment your ecommerce platform by building personalized recommendations and effective marketing campaigns based on your customer needs. The solution approach provided in the blog will help organizations build re-usable architecture pattern and personalization using AWS managed services.

Let’s Architect! Architecting with custom chips and accelerators

Post Syndicated from Luca Mezzalira original https://aws.amazon.com/blogs/architecture/lets-architect-custom-chips-and-accelerators/

It’s hard to imagine a world without computer chips. They are at the heart of the devices that we use to work and play every day. Currently, Amazon Web Services (AWS) is offering customers the next generation of computer chip, with lower cost, higher performance, and a reduced carbon footprint.

This edition of Let’s Architect! focuses on custom computer chips, accelerators, and technologies developed by AWS, such as AWS Nitro System, custom-designed Arm-based AWS Graviton processors that support data-intensive workloads, as well as AWS Trainium, and AWS Inferentia chips optimized for machine learning training and inference.

In this post, we discuss these new AWS technologies, their main characteristics, and how to take advantage of them in your architecture.

Deliver high performance ML inference with AWS Inferentia

As Deep Learning models become increasingly large and complex, the training cost for these models increases, as well as the inference time for serving.

With AWS Inferentia, machine learning practitioners can deploy complex neural-network models that are built and trained on popular frameworks, such as Tensorflow, PyTorch, and MXNet on AWS Inferentia-based Amazon EC2 Inf1 instances.

This video introduces you to the main concepts of AWS Inferentia, a service designed to reduce both cost and latency for inference. To speed up inference, AWS Inferentia: selects and shares a model across multiple chips, places pieces inside the on-chip cache, then streams the data via pipeline for low-latency predictions.

Presenters discuss through the structure of the chip, software considerations, as well as anecdotes from the Amazon Alexa team, who uses AWS Inferentia to serve predictions. If you want to learn more about high throughput coupled with low latency, explore Achieve 12x higher throughput and lowest latency for PyTorch Natural Language Processing applications out-of-the-box on AWS Inferentia on the AWS Machine Learning Blog.

AWS Inferentia shares a model across different chips to speed up inference

AWS Inferentia shares a model across different chips to speed up inference

AWS Lambda Functions Powered by AWS Graviton2 Processor – Run Your Functions on Arm and Get Up to 34% Better Price Performance

AWS Lambda is a serverless, event-driven compute service that enables code to run from virtually any type of application or backend service, without provisioning or managing servers. Lambda uses a high-availability compute infrastructure and performs all of the administration of the compute resources, including server- and operating-system maintenance, capacity-provisioning, and automatic scaling and logging.

AWS Graviton processors are designed to deliver the best price and performance for cloud workloads. AWS Graviton3 processors are the latest in the AWS Graviton processor family and provide up to: 25% increased compute performance, two-times higher floating-point performance, and two-times faster cryptographic workload performance compared with AWS Graviton2 processors. This means you can migrate AWS Lambda functions to Graviton in minutes, plus get as much as 19% improved performance at approximately 20% lower cost (compared with x86).

Comparison between x86 and Arm/Graviton2 results for the AWS Lambda function computing prime numbers

Comparison between x86 and Arm/Graviton2 results for the AWS Lambda function computing prime numbers (click to enlarge)

Powering next-gen Amazon EC2: Deep dive on the Nitro System

The AWS Nitro System is a collection of building-block technologies that includes AWS-built hardware offload and security components. It is powering the next generation of Amazon EC2 instances, with a broadening selection of compute, storage, memory, and networking options.

In this session, dive deep into the Nitro System, reviewing its design and architecture, exploring new innovations to the Nitro platform, and understanding how it allows for fasting innovation and increased security while reducing costs.

Traditionally, hypervisors protect the physical hardware and bios; virtualize the CPU, storage, networking; and provide a rich set of management capabilities. With the AWS Nitro System, AWS breaks apart those functions and offloads them to dedicated hardware and software.

AWS Nitro System separates functions and offloads them to dedicated hardware and software, in place of a traditional hypervisor

AWS Nitro System separates functions and offloads them to dedicated hardware and software, in place of a traditional hypervisor

How Amazon migrated a large ecommerce platform to AWS Graviton

In this re:Invent 2021 session, we learn about the benefits Amazon’s ecommerce Datapath platform has realized with AWS Graviton.

With a range of 25%-40% performance gains across 53,000 Amazon EC2 instances worldwide for Prime Day 2021, the Datapath team is lowering their internal costs with AWS Graviton’s improved price performance. Explore the software updates that were required to achieve this and the testing approach used to optimize and validate the deployments. Finally, learn about the Datapath team’s migration approach that was used for their production deployment.

AWS Graviton2: core components

AWS Graviton2: core components

See you next time!

Thanks for exploring custom computer chips, accelerators, and technologies developed by AWS. Join us in a couple of weeks when we talk more about architectures and the daily challenges faced while working with distributed systems.

Other posts in this series

Looking for more architecture content?

AWS Architecture Center provides reference architecture diagrams, vetted architecture solutions, Well-Architected best practices, patterns, icons, and more!

Lifting and shifting a web application to AWS Serverless: Part 2

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/compute/lifting-and-shifting-a-web-application-to-aws-serverless-part-2/

In part 1, you learn if it is possible to migrate a non-serverless web application to a serverless environment without changing much code. You learn different tools that can help you in this process, like Lambda Web Adaptor and AWS Amplify. By the end, you have migrated an application into a serverless environment.

However, if you test the migrated app, you find two issues. The first one is that the user session is not sticky. Every time you log in, you are logged out unexpectedly from the application. The second one is that when you create a new product, you cannot upload new images of that product.

This final post analyzes each of the problems in detail and shows solutions. In addition, it analyzes the cost and performance of the solution.

Authentication and authorization migration

The original application handled the authentication and authorization by itself. There is a user directory in the database, with the passwords and emails for each of the users. There are APIs and middleware that take care of validating that the user is logged in before showing the application. All the logic for this is developed inside the Node.js/Express application.

However, with the current migrated application every time you log in, you are logged out unexpectedly from the application. This is because the server code is responsible for handling the authentication and the authorization of the users, and now our server is running in an AWS Lambda function and functions are stateless. This means that there will be one function running per request—a request can load all the products in the landing page, get the details for a product, or log in to the site—and if you do something in one of these functions, the state is not shared across.

To solve this, you must remove the authentication and authorization mechanisms from the function and use a service that can preserve the state across multiple invocations of the functions.

There are many ways to solve this challenge. You can add a layer of authentication and session management with a database like Redis, or build a new microservice that is in charge of authentication and authorization that can handle the state, or use an existing managed service for this.

Because of the migration requirements, we want to keep the cost as low as possible, with the fewest changes to the application. The better solution is to use an existing managed service to handle authentication and authorization.

This demo uses Amazon Cognito, which provides user authentication and authorization to AWS resources in a managed, pay as you go way. One rapid approach is to replace all the server code with calls to Amazon Cognito using the AWS SDK. But this adds complexity that can be replaced completely by just invoking Amazon Cognito APIs from the React application.

Using Cognito

For example, when a new user is registered, the application creates the user in the Amazon Cognito user pool directory, as well as in the application database. But when a user logs in to the web app, the application calls Amazon Cognito API directly from the AWS Amplify application. This way minimizes the amount of code needed.

In the original application, all authenticated server APIs are secured with a middleware that validates that the user is authenticated by providing an access token. With the new setup that doesn’t change, but the token is generated by Amazon Cognito and then it can be validated in the backend.

let auth = (req, res, next) => {
    const token = req.headers.authorization;
    const jwtToken = token.replace('Bearer ', '');

    verifyToken(jwtToken)
        .then((valid) => {
            if (valid) {
                getCognitoUser(jwtToken).then((email) => {
                    User.findByEmail(email, (err, user) => {
                        if (err) throw err;
                        if (!user)
                            return res.json({
                                isAuth: false,
                                error: true,
                            });

                        req.user = user;
                        next();
                    });
                });
            } else {
                throw Error('Not valid Token');
            }
        })
        .catch((error) => {
            return res.json({
                isAuth: false,
                error: true,
            });
        });
};

You can see how this is implemented step by step in this video.

Storage migration

In the original application, when a new product is created, a new image is uploaded to the Node.js/Express server. However, now the application resides in a Lambda function. The code (and files) that are part of that function cannot change, unless the function is redeployed. Consequently, you must separate the user storage from the server code.

For doing this, there are a couple of solutions: using Amazon Elastic File System (EFS) or Amazon S3. EFS is a file storage, and you can use that to have a dynamic storage where you upload the new images. Using EFS won’t change much of the code, as the original implementation is using a directory inside the server as EFS provides. However, using EFS adds more complexity to the application, as functions that use EFS must be inside an Amazon Virtual Private Cloud (Amazon VPC).

Using S3 to upload your images to the application is simpler, as it only requires that an S3 bucket exists. For doing this, you must refactor the application, from uploading the image to the application API to use the AWS Amplify library that uploads and gets images from S3.

export function uploadImage(file) {
    const fileName = `uploads/${file.name}`;

    const request = Storage.put(fileName, file).then((result) => {
        return {
            image: fileName,
            success: true,
        };
    });

    return {
        type: IMAGE_UPLOAD,
        payload: request,
    };
}

An important benefit of using S3 is that you can also use Amazon CloudFront to accelerate the retrieval of the images from the cloud. In this way, you can speed up the loading time of your page. You can see how this is implemented step by step in this video.

How much does this application cost?

If you deploy this application in an empty AWS account, most of the usage of this application is covered by the AWS Free Tier. Serverless services, like Lambda and Amazon Cognito, have a forever free tier that gives you the benefits in pricing for the lifetime of hosting the application.

  • AWS Lambda—With 100 requests per hour, an average 10ms invocation and 1GB of memory configured, it costs 0 USD per month.
  • Amazon S3—Using S3 standard, hosting 1 GB per month and 10k PUT and GET requests per month costs 0.07 USD per month. This can be optimized using S3 Intelligent-Tiering.
  • Amazon Cognito—Provides 50,000 monthly active users for free.
  • AWS Amplify—If you build your client application once a week, serve 3 GB and store 1 GB per month, this costs 0.87 USD.
  • AWS Secrets Manager—There are two secrets stored using Secrets Manager and this costs 1.16 USD per month. This can be optimized by using AWS System Manager Parameter Store and AWS Key Management Service (AWS KMS).
  • MongoDB Atlas – Forever free shared cluster.

The total monthly cost of this application is approximately 2.11 USD.

Performance analysis

After you migrate the application, you can run a page speed insight tool, to measure this application’s performance. This tool provides results mostly about the front end and the experience that the user perceives. The results are displayed in the following image. The performance of this website is good, according to the insight tool performance score – it responds quickly and the user experience is good.

Page speed insight tool results

After the application is migrated to a serverless environment, you can do some refactoring to improve further the overall performance. One alternative is whenever a new image is uploaded, it gets resized and formatted into the correct next-gen format automatically using the event driven capabilities that S3 provides. Another alternative is to use Lambda on Edge to serve the right image size for the device, as it is possible to format the images on the fly when serving them from a distribution.

You can run load tests for understanding how your backend and database will perform. For this, you can use Artillery, an open-source library that allows you to run load tests. You can run tests with the expected maximum load your site will get and ensure that your site can handle it.

For example, you can configure a test that sends 30 requests per seconds to see how your application reacts:

config:
  target: 'https://xxx.lambda-url.eu-west-1.on.aws'
  phases:
    - duration: 240
      arrivalRate: 30
      name: Testing
scenarios:
  - name: 'Test main page'
    flow:
      - post:
          url: '/api/product/getProducts/'

This test is performed on the backend APIs, not only testing your backend but also your integration with the MongoDB. After running it, you can see how the Lambda function performs on the Amazon CloudWatch dashboard.

Running this load test helps you understand the limitations of your system. For example, if you run a test with too many concurrent users, you might see that the number of throttles in your function increases. This means that you need to lift the limit of invocations of the functions you can have at the same time.

Or when increasing the requests per second, you may find that the MongoDB cluster starts throttling your requests. This is because you are using the free tier and that has a set number of connections. You might need a larger cluster or to migrate your database to another service that provides a large free tier, like Amazon DynamoDB.

Cloudwatch dashboard

Conclusion

In this two-part article, you learn if it is possible to migrate a non-serverless web application to a serverless environment without changing much code. You learn different tools that can help you in this process, like AWS Lambda Web Adaptor and AWS Amplify, and how to solve some of the typical challenges that we have, like storage and authentication.

After the application is hosted in a fully serverless environment, it can scale up and down to meet your needs. This web application is also performant once the backend is hosted in a Lambda function.

If you need, from here you can start using the strangler pattern to refactor the application to take advantage of the benefits of event-driven architecture.

To see all the steps of the migration, there is a playlist that contains all the tutorials for you to follow.

For more serverless learning resources, visit Serverless Land.

Lifting and shifting a web application to AWS Serverless: Part 1

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/compute/lifting-and-shifting-a-web-application-to-aws-serverless-part-1/

Customers migrating to the cloud often want to get the benefits of serverless architecture. But what is the best approach and is it possible? There are many strategies to do a migration, but lift and shift is often the fastest way to get to production with the migrated workload.

You might also wonder if it’s possible to lift and shift an existing application that runs in a traditional environment to serverless. This blog post shows how to do this for a Mongo, Express, React, and Node.js (MERN) stack web app. However, the discussions presented in this post apply to other stacks too.

Why do a lift and shift migration?

Lift and shift, or sometimes referred to as rehosting the application, is moving the application with as few changes as possible. Lift and shift migrations often allow you to get the new workload in production as fast as possible. When migrating to serverless, lift and shift can bring a workload that is not yet in the cloud or in a serverless environment to use managed and serverless services quickly.

Migrating a non-serverless workload to serverless with lift and shift might not bring all the serverless benefits right away, but it enables the development team to refactor, using the strangler pattern, the parts of the application that might benefit from what serverless technologies offer.

Why migrate a web app to serverless?

Web apps hosted in a serverless environment benefit most from the capability of serverless applications to scale automatically and for paying for what you use.

Imagine that you have a personal web app with little traffic. If you are hosting in a serverless environment, you don’t pay a fixed price to have the servers up and running. Your web app has only a few requests and the rest of the time is idle.

This benefit applies to the opposite case. For an owner of a small ecommerce site running on a server, imagine if a social media influencer with millions of followers recommends one of their products. Suddenly, thousands of requests arrive and make the site unavailable. If the site is hosted on a serverless platform, the application will scale to the traffic that it receives.

Requirements for migration

Before starting a migration, it is important to define the nonfunctional requirements that you need the new application to have. These requirements help when you must make architectural decisions during the migration process.

These are the nonfunctional requirements of this migration:

  • Environment that scales to zero and scales up automatically.
  • Pay as little as possible for idle time.
  • Configure as little infrastructure as possible.
  • Automatic high availability of the application.
  • Minimal changes to the original code.

Application overview

This blog post guides you on how to migrate a MERN application. The original application is hosted in two different servers: One contains the Mongo database and another contains the Node/js/Express and ReactJS applications.

Application overview

This demo application simulates a swag ecommerce site. The database layer stores the products, users, and the purchases history. The server layer takes care of the ecommerce business logic, hosting the product images, and user authentication and authorization. The web layer takes care of all the user interaction and communicates with the server layer using REST APIs.

How the application looks like

These are the changes that you must make to migrate to a serverless environment:

  • Database migration: Migrate the database from on-premises to MongoDB Atlas.
  • Backend migration: Migrate the NodeJS/Express application from on-premises to an AWS Lambda function.
  • Web app migration: Migrate the React web app from on-premises to AWS Amplify.
  • Authentication migration: Migrate the custom-built authentication to use Amazon Cognito.
  • Storage migration: Migrate the local storage of images to use Amazon S3 and Amazon CloudFront.

The following image shows the proposed solution for the migrated application:

Proposed architecture

Database migration

The database is already in a MongoDB vanilla container that has all the data for this application. As MongoDB is the database engine for our stack, their recommended solution to migrate to serverless is to use MongoDB Atlas. Atlas provides a database cluster in the cloud that scales automatically and you pay for what you use.

To get started, create a new Atlas cluster, then migrate the data from the existing database to the serverless one. To migrate the data, you can first dump all the content of the database to a dump folder and then restore it to the cloud:

mongodump --uri="mongodb://<localuser>:<localpassword>@localhost:27017"

mongorestore --uri="mongodb+srv://<user>:<password>@<clustername>.debkm.mongodb.net" .

After doing that, your data is now in the cloud. The next step is to change the configuration string in the server to point to the new database. To see this in action, check this video that shows a walkthrough of the migration.

Backend migration

Migrating the Node.js/Express backend is the most challenging of the layers to migrate to a serverless environment, as the server layer is a Node.js application that runs in a server.

One option for this migration is to use AWS Fargate. Fargate is a serverless container service that allows you to scale automatically and you pay as you go. Another option is to use AWS AppRunner, a container service that auto scales and you also pay as you go. However, neither of these options align with our migration requirements, as they don’t scale to zero.

Another option for the lift and shift migration of this Node.js application is to use Lambda with the AWS Lambda Web Adapter. The AWS Lambda Web Adapter is an open-source project that allows you to build web applications with familiar frameworks, like Express.js, Flask, SpringBoot, and run it on Lambda. You can learn more about this project in its GitHub repository.

Lambda Web Adapter

Using this project, you can create a new Lambda function that has the Express/NodeJS application as the function code. You can lift and shift all the code into the function. If you want a step-by-step tutorial on how to do this, check out this video.

const lambdaAdapterFunction = new Function(this,`${props.stage}-LambdaAdapterFunction`,
            {
                runtime: Runtime.NODEJS_16_X,
                code: Code.fromAsset('backend-app'),
                handler: 'run.sh',
                environment: {
                    AWS_LAMBDA_EXEC_WRAPPER: '/opt/bootstrap',
                    REGION: this.region,
                    ASYNC_INIT: 'true',
                },
                memorySize: 1024,
                layers: [layerLambdaAdapter],
                timeout: Duration.seconds(2),
                tracing: Tracing.ACTIVE,
            }
        );

The next step is to create an HTTP endpoint for the server application. There are three options for doing this: API Gateway, Application Load Balancer (ALB) , or to use Lambda Function URLs. All the options are compatible with Lambda Web Adapter and can solve the challenge for you.

For this demo, choose function URLs, as they are simple to configure and one function URL forwards all routes to the Express server. API Gateway and ALB require more configuration and have separate costs, while the cost of function URLs is included in the Lambda function.

Web app migration

The final layer to migrate is the React application. The best way to migrate the web layer and to adhere to the migration requirements is to use AWS Amplify to host it. AWS Amplify is a fully managed service that provides many features like hosting web applications and managing the CICD process for the web app. It provides client libraries to connect to different AWS resources, and many other features.

Migrating the React application is as simple as creating a new Amplify application in your AWS account and uploading the React application to a code repository like GitHub. This AWS Amplify application is connected to a GitHub branch, and when there is a new commit in this branch, AWS Amplify redeploys the code.

The Amplify application receives configuration parameters like the function URL endpoint (the server URL) using environmental variables.

const amplifyApp = new App(this, `${props.stage}-AmplifyReactShopApp`, {
            sourceCodeProvider: new GitHubSourceCodeProvider({
                owner: config.frontend.owner,
                repository: config.frontend.repository_name,
                oauthToken: SecretValue.secretsManager('github-token'),
            }),
            environmentVariables: {
                REGION: this.region,
                SERVER_URL: props.serverURL,
            },
        });

If you want to see a step-by-step guide on how to make your web layer serverless, you can check this video.

Next steps

However, if you test this migrated app, you will find two issues. The first one is that the user session is not sticky. Every time you log in, you are logged out unexpectedly from the application. The second one is that when you create a new product, you cannot upload new images of that product.

In part two, I analyze each of the problems in detail and find solutions. These issues arise because of the stateless and immutable characteristics of this solution. The next part of this article explains how to solve these issues, also it analyzes costs and performance of the solution.

Conclusion

In this article, you learn if it is possible to migrate a non-serverless web application to a serverless environment without changing much code. You learn different tools that can help you in this process, like the AWS Lambda Web Adaptor and AWS Amplify.

If you want to see the migration in action and learn all the steps for this, there is a playlist that contains all the tutorials for you to follow and learn how this is possible.

For more serverless learning resources, visit Serverless Land.

AWS Week in Review – September 5, 2022

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/aws-week-in-review-september-5-2022/

This post is part of our Week in Review series. Check back each week for a quick roundup of interesting news and announcements from AWS!

As a new week begins, let’s quickly look back at the most significant AWS news from the previous seven days.

Last Week’s Launches
Here are the launches that got my attention last week:

AWS announces open-sourced credentials-fetcher to simplify Microsoft AD access from Linux containers. You can find more in the What’s New post.

AWS Step Functions now has 14 new intrinsic functions that help you process data more efficiently and make it easier to perform data processing tasks such as array manipulation, JSON object manipulation, and math functions within your workflows without having to invoke downstream services or add Task states.

AWS SAM CLI esbuild support is now generally available. You can now use esbuild in the SAM CLI build workflow for your JavaScript applications.

Amazon QuickSight launches a new user interface for dataset management that replaces the existing popup dialog modal with a full-page experience, providing a clearer breakdown of dataset management categories.

AWS GameKit adds Unity support. With this release for Unity, you can integrate cloud-based game features into Win64, MacOS, Android, or iOS games from both the Unreal and Unity engines with just a few clicks.

AWS and VMware announce VMware Cloud on AWS integration with Amazon FSx for NetApp ONTAP. Read more in Veliswa‘s blog post.

The AWS Region in the United Arab Emirates (UAE) is now open. More info in Marcia‘s blog post.

View of Abu Dhabi in the United Arab Emirates

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
A few more blog posts you might have missed:

Easy analytics and cost-optimization with Amazon Redshift Serverless – Four different use cases of Redshift Serverless are discussed in this post.

Building cost-effective AWS Step Functions workflows – In this blog post, Ben explains the difference between Standard and Express Workflows, including costs, migrating from Standard to Express, and some interesting ways of using both together.

How to subscribe to the new Security Hub Announcements topic for Amazon SNS – You can now receive updates about new Security Hub services and features, newly supported standards and controls, and other Security Hub changes.

Deploying AWS Lambda functions using AWS Controllers for Kubernetes (ACK) – With the ACK service controller for AWS Lambda, you can provision and manage Lambda functions with kubectl and custom resources.

For AWS open-source news and updates, here’s the latest newsletter curated by Ricardo to bring you the most recent updates on open-source projects, posts, events, and more.

Upcoming AWS Events
Depending on where you are on this planet, there are many opportunities to meet and learn:

AWS Summits – Come together to connect, collaborate, and learn about AWS. Registration is open for the following in-person AWS Summits: Ottawa (September 8), New Delhi (September 9), Mexico City (September 21–22), Bogotá (October 4), and Singapore (October 6).

AWS Community Days – AWS Community Day events are community-led conferences to share and learn with one another. In September, the AWS community in the US will run events in the Bay Area, California (September 9) and Arlington, Virginia (September 30). In Europe, Community Day events will be held in October. Join us in Amersfoort, Netherlands (October 3), Warsaw, Poland (October 14), and Dresden, Germany (October 19).

That’s all from me for this week. Come back next Monday for another Week in Review!

— Danilo

A multi-dimensional approach helps you proactively prepare for failures, Part 3: Operations and process resiliency

Post Syndicated from Piyali Kamra original https://aws.amazon.com/blogs/architecture/a-multi-dimensional-approach-helps-you-proactively-prepare-for-failures-part-3-operations-and-process-resiliency/

In Part 1 and Part 2 of this series, we discussed how to build application layer and infrastructure layer resiliency.

In Part 3, we explore how to develop resilient applications, and the need to test and break our operational processes and run books. Processes are needed to capture baseline metrics and boundary conditions. Detecting deviations from accepted baselines requires logging, distributed tracing, monitoring, and alerting. Testing automation and rollback are part of continuous integration/continuous deployment (CI/CD) pipelines. Keeping track of network, application, and system health requires automation.

In order to meet recovery time and point objective (RTO and RPO, respectively) requirements of distributed applications, we need automation to implement failover operations across multiple layers. Let’s explore how a distributed system’s operational resiliency needs to be addressed before it goes into production, after it’s live in production, and when a failure happens.

Pattern 1: Standardize and automate AWS account setup

Create processes and automation for onboarding users and providing access to AWS accounts according to their role and business unit, as defined by the organization. Federated access to AWS accounts and organizations simplifies cost management, security implementation, and visibility. Having a strategy for a suitable AWS account structure can reduce the blast radius in case of a compromise.

  1. Have auditing mechanisms in place. AWS CloudTrail monitors compliance, improving security posture, and auditing all the activity records across AWS accounts.
  2. Practice the least privilege security model when setting up access to the CloudTrail audit logs plus network and applications logs. Follow best practices on service control policies and IAM boundaries to help ensure your AWS accounts stay within your organization’s access control policies.
  3. Explore AWS Budgets, AWS Cost Anomaly Detection, and AWS Cost Explorer for cost-optimizing techniques. The AWS Compute Optimizer and Instance Scheduler on AWS resource resizing and auto-shutdown for non-working hours. A Beginner’s Guide to AWS Cost Management explores multiple cost-optimization techniques.
  4. Use AWS CloudFormation and AWS Config to detect infrastructure drift and take corrective actions to make resources compliant, as demonstrated in Figure 1.
Compliance control and drift detection

Figure 1. Compliance control and drift detection

Pattern 2: Documenting knowledge about the distributed system

Document high-level infrastructure and dependency maps.

Define availability characteristics of distributed system. Systems have components with varying RTO and RPO needs. Document application component boundaries and capture dependencies with other infrastructure components, including Domain Name System (DNS), IAM permissions; and access patterns, secrets, and certificates. Discover dependencies through solutions, such as Workload Discovery on AWS, to plan resiliency methods and ensure the order of execution of various steps during failover are correct.

Capture non-functional requirements (NFRs), such as business key performance indicators (KPIs), RTO, and RPO, for your composing services. NFRs are quantifiable and define system availability, reliability, and recoverability requirements. They should include throughput, page-load, and response time requirements. Quantify the RTO and RPO of different components of the distributed system by defining them. The KPIs measure if you are meeting the business objectives. As mentioned in Part 2: Infrastructure layer, RTO and RPO help define the failover and data recovery procedures.

Pattern 3: Define CI/CD pipelines for application code and infrastructure components

Establish a branching strategy. Implement automated checks for version and tagging compliance in feature/sprint/bug fix/hot fix/release candidate branches, according to your organization’s policies. Define appropriate release management processes and responsibility matrices, as demonstrated in Figures 2 and 3.

Test at all levels as part of an automated pipeline. This includes security, unit, and system testing. Create a feedback loop that provides the ability to detect issues and automate rollback in case of production failures, which are indicated by business KPI negative impact and other technical metrics.

Define the release management process

Figure 2. Define the release management process

Sample roles and responsibility matrix

Figure 3. Sample roles and responsibility matrix

Pattern 4: Keep code in a source control repository, regardless of GitOps

Merge requests and configuration changes follow the same process as application software. Just like application code, manage infrastructure as code (IaC) by checking the code into a source control repository, submitting pull requests, scanning code for vulnerabilities, alerting and sending notifications, running validation tests on deployments, and having an approval process.

You can audit your infrastructure drift, design reusable and repeatable patterns, and adhere to your distributed application’s RTO objectives by building your IaC (Figure 4). IaC is crucial for operational resilience.

CI/CD pipeline for deploying IaC

Figure 4. CI/CD pipeline for deploying IaC

Pattern 5: Immutable infrastructure

An immutable deployment pipeline launches a set of new instances running the new application version. You can customize immutability at different levels of granularity depending on which infrastructure part is being rebuilt for new application versions, as in Figure 5.

The more immutable infrastructure components being rebuilt, the more expensive deployments are in both deployment time and actual operational costs. Immutable infrastructure also is easier to rollback.

Different granularity levels of immutable infrastructure

Figure 5. Different granularity levels of immutable infrastructure

Pattern 6: Test early, test often

In a shift-left testing approach, begin testing in the early stages, as demonstrated in Figure 6. This can surface defects that can be resolved in a more time- and cost-effective manner compared with after code is released to production.

Shift-left test strategy

Figure 6. Shift-left test strategy

Continuous testing is an essential part of CI/CD. CI/CD pipelines can implement various levels of testing to reduce the likelihood of defects entering production. Testing can include: unit, functional, regression, load, and chaos.

Continuous testing requires testing and breaking existing boundary conditions, and updating test cases if the boundaries have changed. Test cases should test distributed systems’ idempotency. Chaos testing benefits our incidence response mechanisms for distributed systems that have multiple integration points. By testing our auto scaling and failover mechanisms, chaos testing improves application performance and resiliency.

AWS Fault Injection Simulator (AWS FIS) is a service for chaos testing. An experiment template contains actions, such as StopInstance and StartInstance, along with targets on which the test will be performed. In addition, you can mention stop conditions and check if they triggered the required Amazon CloudWatch alarms, as demonstrated in Figure 7.

AWS Fault Injection Simulator architecture for chaos testing

Figure 7. AWS Fault Injection Simulator architecture for chaos testing

Pattern 7: Providing operational visibility

In production, operational visibility across multiple dimensions is necessary for distributed systems (Figure 8). To identify performance bottlenecks and failures, use AWS X-Ray and other open-source libraries for distributed tracing.

Write application, infrastructure, and security logs to CloudWatch. When metrics breach alarm thresholds, integrate the corresponding alarms with Amazon Simple Notification Service or a third-party incident management system for notification.

Monitoring services, such as Amazon GuardDuty, are used to analyze CloudTrail, virtual private cloud flow logs, DNS logs, and Amazon Elastic Kubernetes Service audit logs to detect security issues. Monitor AWS Health Dashboard for maintenance, end-of-life, and service-level events that could affect your workloads. Follow the AWS Trusted Advisor recommendations to ensure your accounts follow best practices.

Dimensions for operational visibility

Figure 8. Dimensions for operational visibility (click the image to enlarge)

Figure 9 explores various application and infrastructure components integrating with AWS logging and monitoring components for increased problem detection and resolution, which can provide operational visibility.

Tooling architecture to provide operational visibility

Figure 9. Tooling architecture to provide operational visibility

Having an incident response management plan is an important mechanism for providing operational visibility. Successful execution of this requires educating the stakeholders on the AWS shared responsibility model, simulation of anticipated and unanticipated failures, documentation of the distributed system’s KPIs, and continuous iteration. Figure 10 demonstrates the features of a successful incidence response management plan.

An incidence response management plan

Figure 10. An incidence response management plan (click the image to enlarge)

Conclusion

In Part 3, we discussed continuous improvement of our processes by testing and breaking them. In order to understand the baseline level metrics, service-level agreements, and boundary conditions of our system, we need to capture NFRs. Operational capabilities are required to capture deviations from baseline, which is where alerting, logging, and distributed tracing come in. Processes should be defined for automating frequent testing in CI/CD pipelines, detecting network issues, and deploying alternate infrastructure stacks in failover regions based on RTOs and RPOs. Automating failover steps depends on metrics and alarms, and by using chaos testing, we can simulate failover scenarios.

Prepare for failure, and learn from it. Working to maintain resilience is an ongoing task.

Want to learn more?

Integrating Salesforce with AWS DynamoDB using Amazon AppFlow bi-directionally

Post Syndicated from Abhijit Vaidya original https://aws.amazon.com/blogs/architecture/integrating-salesforce-with-aws-dynamodb-using-amazon-appflow-bi-directionally/

In this blog post, we demonstrate how to integrate Salesforce Lightning with Amazon DynamoDB by using Amazon AppFlow and Amazon EventBridge services bi-directionally. This is an event-driven, serverless-based microservice, allowing Salesforce users to update configuration data stored in DynamoDB tables without giving AWS account access from AWS Command Line Interface or AWS Management Console.

This architecture describes a contact center application that utilizes DynamoDB database to store configuration data, including holiday data, across different global regions. Updating this data in a table is a manual process, which includes creating a support ticket and waiting for completion of the support request. The architecture herein allows authorized business users to update the configuration data in DynamoDB directly from the Salesforce screen and not relying on manual update process.

Solution overview

As demonstrated in Figure 1, Amazon AppFlow consumes events payload from salesforce and Lambda updates the DynamoDB table after processing the payload. In parallel, a scheduled based flow sends response back to salesforce object as a notification and sends a SNS email notification to users. Contact center application (Amazon Connect) reads data from DynamoDB table.

Architecture overview

Figure 1. Architecture overview

  1. Event (data add or delete) occurring on a particular object in Salesforce is captured by Amazon AppFlow (event-based flow); event payload displays as “Input” in AWS environment.
  2. An EventBridge bus receives the “Input” payload.
  3. The EventBridge bus triggers the AWS Lambda (Lambda-1).
  4. Lambda-1 processes the “Input” payload, then performs a write operation (data add or delete) on a DynamoDB table.
  5. A write operation on the table triggers DynamoDB streams.
  6. DynamoDB stream triggers Lambda (Lambda-2).
  7. Lambda-2 processes the payload from DynamoDB streams. It saves the results in .csv file format, with a “Success” or “Fail” flag. This .csv file is uploaded to an S3 bucket.
  8. A second flow (schedule-based) is configured in Amazon AppFlow. This reads the S3 bucket at a regular interval of time to find new .csv files created by Lambda-2.
  9. A schedule-based flow transfers the .csv file data as an event-status output to the Salesforce object, notifying the user that their event has been successfully handled in DynamoDB table.
  10. In parallel, DynamoDB streams trigger Lambda (Lambda-3), which processes the payload and initiates an Amazon Simple Notification Service (Amazon SNS) notification based on the status of the event request.
  11. Amazon SNS sends an email to the user detailing that the event created in the Salesforce object was successfully completed in DynamoDB table.
  12. If any of the two flows break due to any unforeseen events, their statuses are instantly captured and streamed to an EventBridge bus.
  13. The EventBridge bus triggers Lambda (Lambda-5).
  14. Lambda-5 tries to analyze the error causing failure and tries to get the flow to a working state again. If Lambda-5 fails, it initiates an Amazon SNS email to the solution support team to manually fix the Amazon AppFlow error and get the solution active again.
  15. Meanwhile, whenever an Amazon Connect contact center receives a call, it triggers Lambda (Lambda-4), which holds read-only access to DynamoDB table.
  16. Lambda-4 fetches the data stored by Lambda-1 in DynamoDB table and provides that data to a contact center in Amazon Connect.

Prerequisites

  • An AWS account with permissions to access all the required
  • An active Salesforce account with administration-level permissions set
  • Python 3.X version setup for developing Lambda-1 to -5

Implementation and development

1. Development steps on the Salesforce end

Note: We recommend working with a Salesforce expert. These steps can help initiate the development from Salesforce end.

a. Use the Platform Event feature to allow the data flow from Salesforce environment to AWS environment and then back to Salesforce from AWS environment using Amazon AppFlow.
b. Salesforce Connected Apps and web server flow used for integrating Amazon AppFlow with Salesforce.
c. New permissions set and new integration users are created to restrict the access to custom object.

2. Development steps on the AWS end

a. Create a new connection in Amazon AppFlow with “Salesforce” as the source
The “Client ID” and “Client Secret” of Salesforce Managed Connected App are stored in AWS Secrets Manager, which is encrypted by custom keys generated in AWS Key Management Service.

To setup an Amazon AppFlow connection with Salesforce, a stand-alone Lambda function is created using Python Boto3 API. This creates a connection in Amazon AppFlow using the “Client ID” and “Client Secret” of Salesforce connected app.

For more details regarding setting up the Salesforce connection in Amazon AppFlow, refer to the Amazon AppFlow User Guide.

b. Create new event-based input flow in Amazon AppFlow, using Salesforce as the source with the newly created connection
Select the “Salesforce events” option as per the business use case. For representation in this blog, “Telephony” is chosen as salesforce events. Select Amazon EventBridge as the destination. Create new “partner event source” for successful creation of input flow, as in Figure 2.

Configure an event-based flow in Amazon AppFlow

Figure 2. Configure an event-based flow in Amazon AppFlow

c. Handling large size input flow event payloads
Post successful creation of “Partner event source”, specify the S3 bucket for events that are larger than 256 KB, Amazon AppFlow sends a URL of the S3 object to the event bus instead of the event payload.

d. Configuring details for input flow
Select trigger pattern of input flow as “Run flow on event”, as shown in Figure 3.

Trigger pattern for creating input flow

Figure 3. Trigger pattern for creating input flow

As displayed in Figure 4, we can configure data field mapping, validation rules, and filters with Amazon AppFlow. This enables us to enrich and modify event data before it is sent to the event bus. Post this, input flow create action is complete.

Mapping Salesforce object fields with Amazon EventBridge bus

Figure 4. Mapping Salesforce object fields with Amazon EventBridge bus

e. Associating Amazon AppFlow generated partner event source with the event bus in the Amazon EventBridge dashboard
Before activating the flow, access the Amazon EventBridge console to associate the AppFlow generated partner-event-source with the event bus (Figure 5).

Associating input flow partner event source with the Amazon EventBridge bus

Figure 5. Associating input flow partner event source with the Amazon EventBridge bus

f. Post Amazon EventBridge bus association, activate the input flow
After associating the bus with input flow, navigate back to Amazon AppFlow console and click the “Activate flow” button for the input flow. Once active, input flow is ready to consume the event payload from Salesforce.

g. Amazon EventBridge bus triggering Lambda function
The EventBridge bus receives an event payload from the input flow and triggers Lambda (Lambda-1) to process that raw event payload and write the output results in a designated DynamoDB table. A sample of event input payload is in Figure 6. This payload content depends on the use case for which developer is working.

Input event payload sample from Salesforce

Figure 6. Input event payload sample from Salesforce

Lambda-1 adds the record-ID in the DynamoDB table, which is a unique event ID for each Salesforce event as shown in Figure 7.

Data added in Amazon DynamoDB table by Lambda-1

Figure 7. Data added in Amazon DynamoDB table by Lambda-1

h. Configuring DynamoDB streams
Within “Export and Streams” option in the DynamoDB table, enable the “DynamoDB stream details” and in the trigger section click on “Create trigger” option and select  Lambda-2 and Lambda -3, as detailed in Figure 8.

Configuring Amazon DynamoDB streams

Figure 8. Configuring Amazon DynamoDB streams

Lambda-2 stores the event output results and a success flag value in a .csv file that is created for every unique event; the .csv file is uploaded to an S3 bucket with the file name structure “Salesforce event recorded-event action-timestamp.csv”. For example:

Example 1: “abcd1234-event-created- 2022-05-19-11_23_51.csv” (data added)
Example 2: “abcd1234-event-deleted- 2022-05-19-11_24_50.csv” (data deleted)

i. Create new schedule-based flow (output flow) in Amazon AppFlow
The source is the S3 bucket folder where the .csv file is uploaded by Lambda-2. Select the destination as “Salesforce”, and choose the Salesforce object that is used to create the input flow (Figure 9). Revisit Step b for reference.

Configuring a schedule-based output flow

Figure 9. Configuring a schedule-based output flow

Output flow sends a response back to the same Salesforce object from which data addition/deletion event request was made. This confirms to the user that a data addition/deletion event created in Salesforce was successfully invoked in Dynamo DB table as well.

j. Error handling in output flow
In case output flow fails to write the response back to the Salesforce object, choose the option “Stop the current flow run”.

k. Configuring output flow as a run-on schedule
Output flow is a schedule-based flow that runs at specific time. Within the flow trigger window, select “Run flow on schedule”. Update the other fields, such as “Repeats”, “Every”, “Start date”, and “Starting at” per your specific needs. Within “Transfer mode”, select “Incremental transfer”. Refer to Figure 10.

Trigger pattern for schedule-based output flow

Figure 10. Trigger pattern for schedule-based output flow

l. Amazon AppFlow to Salesforce object mapping for output flow
Select Mapping method as “Manually map fields” and Destination record preference as “Upsert records”, as in Figure 11.

Output Flow will update the event record status in the Salesforce object, with success status flag value in the .csv file based on the unique “Record ID” that every Salesforce event payload contains. Once the field mapping is completed, output flow is active.

Manually mapping data fields with Salesforce

Figure 11. Manually mapping data fields with Salesforce

m. Real-time monitoring and failure handling
In case input/output flow breaks for unforeseen reasons, a rule is configured in EventBridge bus console that invokes Lambda (Lambda-5). Lambda-5 tries to handle the error and reactivate the flow. In case this action fails, Lambda sends an Amazon SNS email to the solution support team informing of the failure in Amazon AppFlow and the cause.

n. Integrating DynamoDB with Amazon Connect
Lambda (Lambda-4) is configured with contact center in Amazon Connect. As the call comes to contact center, Lambda-4 fetches the relevant data from the DynamoDB table. Amazon Connect operates per this data.

Cleanup

To avoid incurring future charges, delete any AWS resources that are no longer needed.

Conclusion

This post demonstrates the approach for developing an event-driven, serverless application that integrates DynamoDB with Salesforce using Amazon AppFlow bi-directionally. The contact center is based in Amazon Connect and functions dependent on the real-time data in a DynamoDB table—without manual intervention. The manual process can take a minimum of 24 hours, but the same action can be automatically completed using a self-service, UI-based form in the user’s Salesforce account.

This solution can be tailored depending on the business or technical requirement, differing how the data is consumed by multiple AWS services.

Deploying AWS Lambda functions using AWS Controllers for Kubernetes (ACK)

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/deploying-aws-lambda-functions-using-aws-controllers-for-kubernetes-ack/

This post is written by Rajdeep Saha, Sr. SSA, Containers/Serverless.

AWS Controllers for Kubernetes (ACK) allows you to manage AWS services directly from Kubernetes. With the ACK service controller for AWS Lambda, you can provision and manage Lambda functions with kubectl and custom resources. With ACK, you can have a single consolidated approach to managing container workloads and other AWS services, such as Lambda, directly from Kubernetes without needing additional infrastructure automation tools.

This post walks you through deploying a sample Lambda function from a Kubernetes cluster provided by Amazon EKS.

Use cases

Some of the use cases for provisioning Lambda functions from ACK include:

  • Your organization already has a DevOps process to deploy resources into the Amazon EKS cluster using Kubernetes declarative YAMLs (known as manifest files). With ACK for AWS Lambda, you can now use manifest files to provision Lambda functions without creating separate infrastructure as a code template.
  • Your project has implemented GitOps with Kubernetes. With GitOps, git becomes the single source of truth, and all the changes are done via git repo. In this model, Kubernetes continuously reconciles the git repo (desired state) with the resources running inside the cluster (current state). If any differences are found, the GitOps process automatically implements changes to the cluster from the git repo. Using ACK for AWS Lambda, since you are creating the Lambda function using Kubernetes custom resource, the GitOps model is applied for Lambda.
  • Your organization has established permissions boundaries for different users and groups using role-based access control (RBAC) and IAM roles for service accounts (IRSA). You can reuse this security model for Lambda without having to create new users and policies.

How ACK for AWS Lambda works

  1. The ‘Ops’ team deploys the ACK service controller for Lambda. This controller runs as a pod within the Amazon EKS cluster.
  2. The controller pod needs permission to read the Lambda function code and create the Lambda function. The Lambda function code is stored as a zip file in an S3 bucket for this example. The permissions are granted to the pod using IRSA.
  3. Each AWS service has separate ACK service controllers. This specific controller for AWS Lambda can act on the custom resource type ‘Function’.
  4. The ‘Dev’ team deploys Kubernetes manifest file with custom resource type ‘Function’. This manifest file defines the necessary fields required to create the function, such as S3 bucket name, zip file name, Lambda function IAM role, etc.
  5. The ACK service controller creates the Lambda function using the values from the manifest file.

Prerequisites

You need a few tools before deploying the sample application. Ensure that you have each of the following in your working environment:

This post uses shell variables to make it easier to substitute the actual names for your deployment. When you see placeholders like NAME=<your xyz name>, substitute in the name for your environment.

Setting up the Amazon EKS cluster

  1. Run the following to create an Amazon EKS cluster. The following single command creates a two-node Amazon EKS cluster with a unique name.
    eksctl create cluster
  2. It may take 15–30 minutes to provision the Amazon EKS cluster. When the cluster is ready, run:
    kubectl get nodes
  3. The output shows the following:
    Output
  4. To get the Amazon EKS cluster name to use throughout the walkthrough, run:
    eksctl get cluster
    
    export EKS_CLUSTER_NAME=<provide the name from the previous command>

Setting up the ACK Controller for Lambda

To set up the ACK Controller for Lambda:

  1. Install an ACK Controller with Helm by following these instructions:
    – Change ‘export SERVICE=s3’ to ‘export SERVICE=lambda’.
    – Change ‘export AWS_REGION=us-west-2’ to reflect your Region appropriately.
  2. To configure IAM permissions for the pod running the Lambda ACK Controller to permit it to create Lambda functions, follow these instructions.
    – Replace ‘SERVICE=”s3”’ with ‘SERVICE=”lambda”’.
  3. Validate that the ACK Lambda controller is running:
    kubectl get pods -n ack-system
  4. The output shows the running ACK Lambda controller pod:
    Output

Provisioning a Lambda function from the Kubernetes cluster

In this section, you write a sample “Hello world” Lambda function. You zip up the code and upload the zip file to an S3 bucket. Finally, you deploy that zip file to a Lambda function using the ACK Controller from the EKS cluster you created earlier. For this example, use Python3.9 as your language runtime.

To provision the Lambda function:

  1. Run the following to create the sample “Hello world” Lambda function code, and then zip it up:
    mkdir my-helloworld-function
    cd my-helloworld-function
    cat << EOF > lambda_function.py 
    import json
    
    def lambda_handler(event, context):
        # TODO implement
        return {
            'statusCode': 200,
            'body': json.dumps('Hello from Lambda!')
        }
    EOF
    zip my-deployment-package.zip lambda_function.py
    
  2. Create an S3 bucket following the instructions here. Alternatively, you can use an existing S3 bucket in the same Region of the Amazon EKS cluster.
  3. Run the following to upload the zip file into the S3 bucket from the previous step:
    export BUCKET_NAME=<provide the bucket name from step 2>
    aws s3 cp  my-deployment-package.zip s3://${BUCKET_NAME}
  4. The output shows:
    upload: ./my-deployment-package.zip to s3://<BUCKET_NAME>/my-deployment-package.zip
  5. Create your Lambda function using the ACK Controller. The full spec with all the available fields is listed here. First, provide a name for the function:
    export FUNCTION_NAME=hello-world-s3-ack
  6. Create and deploy the Kubernetes manifest file. The command at the end, kubectl create -f function.yaml submits the manifest file, with kind as ‘Function’. The ACK Controller for Lambda identifies this custom ‘Function’ object and deploys the Lambda function based on the manifest file.
    export AWS_ACCOUNT_ID=$(aws sts get-caller-identity --query "Account" --output text)
    export LAMBDA_ROLE="arn:aws:iam::${AWS_ACCOUNT_ID}:role/lambda_basic_execution"
    
    cat << EOF > lambdamanifest.yaml 
    apiVersion: lambda.services.k8s.aws/v1alpha1
    kind: Function
    metadata:
     name: $FUNCTION_NAME
     annotations:
       services.k8s.aws/region: $AWS_REGION
    spec:
     name: $FUNCTION_NAME
     code:
       s3Bucket: $BUCKET_NAME
       s3Key: my-deployment-package.zip
     role: $LAMBDA_ROLE
     runtime: python3.9
     handler: lambda_function.lambda_handler
     description: function created by ACK lambda-controller e2e tests
    EOF
    kubectl create -f lambdamanifest.yaml
    
  7. The output shows:
    function.lambda.services.k8s.aws/< FUNCTION_NAME> created
  8. To retrieve the details of the function using a Kubernetes command, run:
    kubectl describe function/$FUNCTION_NAME
  9. This Lambda function returns a “Hello world” message. To invoke the function, run:
    aws lambda invoke --function-name $FUNCTION_NAME  response.json
    cat response.json
    
  10. The Lambda function returns the following output:
    {"statusCode": 200, "body": "\"Hello from Lambda!\""}

Congratulations! You created a Lambda function from your Kubernetes cluster.

To learn how to provision the Lambda function using the ACK controller from an OCI container image instead of a zip file in an S3 bucket, follow these instructions.

Cleaning up

This section cleans up all the resources that you have created. To clean up:

  1. Delete the Lambda function:
    kubectl delete function $FUNCTION_NAME
  2. If you have created a new S3 bucket, delete it by running:
    aws s3 rm s3://${BUCKET_NAME} --recursive
    aws s3api delete-bucket --bucket ${BUCKET_NAME}
  3. Delete the EKS cluster:
    eksctl delete cluster --name $EKS_CLUSTER_NAME
  4. Delete the IAM role created for the ACK Controller. Get the IAM role name by running the following command, then delete the role from the IAM console:
    echo $ACK_CONTROLLER_IAM_ROLE

Conclusion

This blog post shows how AWS Controllers for Kubernetes enables you to deploy a Lambda function directly from your Amazon EKS environment. AWS Controllers for Kubernetes provides a convenient way to connect your Kubernetes applications to AWS services directly from Kubernetes.

ACK is open source: you can request new features and report issues on the ACK community GitHub repository.

For more serverless learning resources, visit Serverless Land.