Today, we’re excited to announce that AWS Chatbot has been renamed to Amazon Q Developer, representing an enhancement to developer productivity through generative AI-powered capabilities.
This update represents more than a name change – it’s an enhancement of our chat-based DevOps capabilities. By combining AWS Chatbot’s proven functionality with Amazon Q’s generative AI capabilities, we’re providing developers with more intuitive, efficient tools for cloud resource management.
Transition for Existing Users
The transition to Amazon Q Developer maintains compatibility with most workflows. Current AWS Chatbot users should experience no disruption to their configurations, permissions, or established processes, except for the following use cases.
Notifications: If you are using Q in chat applications to send notifications, then you don’t need to make any changes. Your notifications will start showing “Amazon Q” as the sender.
Manual commands: The visible change is the new “@Amazon Q” command replacing the previous “@aws” mention in chat channels. If you are running commands manually, then you will use “@Amazon Q” instead of “@aws”.
Tip: it is faster to type @Q. The chat platform displays auto complete recommendations with the matching app in the channel.
Programmatic commands: Your Slack Automation Workflows that trigger commands within the AWS Chatbot won’t change with this renaming. If you are sending messages to your Slack channels programmatically using Webhooks or the API with “@aws”, you’ll need to change how you invoke the app programmatically. For more information, see Updating Slack bot user app mentions when sending messages to chat channels programmatically.
All service APIs, SDK endpoints, and AWS Identity and Access Management (IAM) permissions remain unchanged, ensuring business continuity.
We’ve maintained the original AWS ChatBot accessibility by offering Amazon Q Developer’s chat features through the Free tier. This ensures that teams of all sizes can benefit from these enhanced capabilities without additional costs. The renamed service is accessible in all commercial regions, maintaining the same geographical reach as the original AWS Chatbot service.
Security remains paramount with Amazon Q Developer. The service maintains all existing security controls, including AWS Organizations Service Control Policies and chat application policies. Organizations can precisely control access to resources and features through granular IAM permissions and channel-specific guardrails. To take advantage of generative AI capabilities organizations will need to add to the configuration of their channel permissions.
Enhanced Chat Capabilities for DevOps
Amazon Q Developer integration with Microsoft Teams and Slack transforms these chat applications into powerful DevOps command centers, where team members can monitor, diagnose, and optimize their AWS resources and applications. Amazon Q Developer in chat applications provide real-time visibility into environment states, helping team members quickly identify which resources are operational or experiencing issues.
Team members can reduce incident response times and monitor performance issues, traffic spikes, infrastructure events, and security threats through DevOps tooling that enables custom notifications with team member tagging for critical application events, interactive action buttons and aliases for telemetry retrieval, and command execution in chat channels.
Amazon Q in Slack channel
Building on existing features like custom notifications and actions, command aliases, and Amazon Bedrock Agents integration, Amazon Q Developer uses natural language processing to understand context and intent. For example, when investigating resources in a region, you can ask, “What EC2 instances are in us-east-1?”. This natural language understanding streamlines interactions and improves efficiency.
Ask Amazon Q about resources in AWS Account
Amazon Q Developer can be used for more comprehensive resource management and status monitoring in chat channels. It can be used to send alerts to chat channels on Amazon CloudWatch metrics for monitoring, or can be used to explore resources across regions or within an account. DevOps teams can execute queries, such as count all VPCs in a region, listing all subnets in a VPC or providing all details for Amazon Elastic Compute Cloud (EC2) instances in a region, such as “provide all details for EC2 instances in us-east-1”, providing better visibility into infrastructure.
Use Amazon Q to query AWS resources information
Getting Started
Setting up Amazon Q Developer involves a straightforward process through the Amazon Q Developer console or the AWS SDK. To interact with Amazon Q Developer’s generative AI capabilities, start by adding appropriate managed policies (AmazonQDeveloperAccess or AmazonQFullAccess) to your IAM roles. Your teams can then customize their notification preferences, set up automated responses, and configure security guardrails according to their specific requirements.
We’re excited to see how you and your teams leverage these enhanced capabilities to streamline their DevOps workflows and improve collaboration.
About the Author
Aaron Sempf is Next Gen Tech Lead for the AWS Partner Organization in Asia-Pacific and Japan. With over twenty years in distributed system engineering design and development, he focuses on solving for large scale complex integration and event driven systems. In his spare time, he can be found coding prototypes for autonomous robots, IoT devices, distributed solutions and designing Agentic Architecture patterns for GenAI assisted business automation.
AWS CloudFormation enables you to model and provision your cloud application infrastructure as code-base templates. Whether you prefer writing templates directly in JSON or YAML, or using programming languages like Python, Java, and TypeScript with the AWS Cloud Development Kit (CDK), CloudFormation and CDK provide the flexibility you need. For organizations adopting multi-account strategies, CloudFormation StackSets offers a powerful capability to deploy resources across multiple regions and accounts in parallel.
Last year, we delivered broad set of enhancements that accelerated the development cycle, simplified troubleshooting, and introduced new deployment safety and configuration governance capabilities. Let’s dive into the key launches that shaped CloudFormation in 2024.
Development cycle improvements
Deploy stacks up to 40% faster with optimistic stabilization and configuration complete
In March, we introduced optimistic stabilization with the new CONFIGURATION_COMPLETE event, delivering up to 40% faster stack creation times. This new event signals that CloudFormation has created the resource and applied the configuration as defined in the stack template, allowing us to begin parallel creation of dependent resources. For example, if your stack contains resource B that depends on resource A, CloudFormation will now start provisioning resource B when resource A reaches the CONFIGURATION_COMPLETE state, rather than waiting for full stabilization. Read How we sped up AWS CloudFormation deployments with optimistic stabilization to learn more.
Figure 1: CloudFormation’s old and new deployment strategy
Catch template errors before deployment with early validation
In March, we launched early resource properties validation checks. This feature validates your stack operation upfront for invalid resource property errors, helping you fail fast and minimize the steps required for a successful deployment. Previously, you had to wait until CloudFormation attempted to provision a resource before discovering property-related errors. Now, we validate your template before deploying the first resource and provide clear error messages upfront.
Figure 2: CloudFormation’s early template properties validation feature
Safely clean up failed stacks with enhanced deletion controls
In May, we enhanced the DeleteStack API with a new DeletionMode parameter, allowing you to safely delete stacks that are in DELETE_FAILED state. By passing the FORCE_DELETE_STACK value to this parameter, you can now resolve stuck stacks more efficiently during your development and testing cycles.
Accelerate feedback loops with CloudFormation custom resource timeout controls
In June, we introduced the ServiceTimeout property for custom resources. This new capability allows you to set custom timeout values for your custom resource logic execution. Previously, custom resources had a fixed one-hour timeout, which could lead to long wait times when debugging custom resource logic. Now, you can set appropriate timeout values to accelerate your development feedback loops. Refer to the custom resourcesdocumentation to learn more about the ServiceTimeout property.
Figure 3: CloudFormation’s ServiceTimeout property for Custom resource
Streamlined Troubleshooting Experience
Resolve deployment issues faster with one-click CloudTrail access
In May, we launched integration with AWS CloudTrail in the Events tab of the CloudFormation console. Troubleshooting some failed stack operations can be time-consuming, so we have streamlined this process by providing direct links from stack operation events to relevant CloudTrail events. When you click ‘Detect Root Cause’ in the CloudFormation Console, you’ll now see a pre-configured CloudTrail deep-link to the API events generated by your stack operation, eliminating multiple manual steps from the troubleshooting process.
Figure 4: CloudFormation troubleshooting with CloudTrail integration
Visualize your entire deployment process with timeline view
In November, we launched deployment timeline view. It gives you unprecedented visibility into your stack operations. This visual tool shows the sequence of actions CloudFormation takes during a deployment, helping you understand resource dependencies and provisioning duration. You can see which resources are being created in parallel, track their status through color-coding, and quickly identify bottlenecks in your deployments.
Get instant troubleshooting help with Amazon Q Developer
We integrated Amazon Q Developer to provide AI-powered assistance for troubleshooting. When you encounter a failed stack operation, you can now click “Diagnose with Q” to receive a clear, human-readable analysis of the error. Need more help? The “Help me resolve” button provides actionable steps tailored to your specific scenario.
Figure 6: CloudFormation troubleshooting with Q feature
We’ve also improved how change sets handle references. When referenced values are available before deployment, Change sets can now resolve them to their expected values, giving you a more accurate preview of your planned changes.
Figure 7: CloudFormation’s change sets feature
Easy onboarding to Infrastructure-as-Code (IaC)
Eliminate weeks of manual effort with IaC Generator
In February, we launched the CloudFormation IaC Generator, a capability addressing one of our customers’ biggest challenges: onboarding existing cloud resources to CloudFormation. This feature makes it easier to generate CloudFormation templates for existing AWS resources. You can now onboard workloads to IaC in minutes instead of spending weeks writing templates manually.
The IaC generator supports over 600 AWS resource types and provides recommendations for related resources. For instance, when you select an S3 bucket, it automatically suggests including associated bucket policies. You can use the generated templates to import resources into CloudFormation, download them for deployment.
Figure 8: CloudFormation’s IaC Generator
In August, we enhanced the IaC Generator with two improvements. First, we added a graphical summary view that helps you quickly find resources after the account scan completes. Second, we integrated with AWS Infrastructure Composer to visualize your application architecture, making it easier to understand resource relationships and configurations.
Figure 9: IaC generator resource scan
Proactive Control Improvements
In November, we launched major enhancements to CloudFormation Hooks, giving you easier ways to author proactive configuration controls and more points to enforce them with your cloud infrastructure provisioning.
CloudFormation Hooks for stack and change set target invocation points
First, we introduced stack and change set target invocation points for CloudFormation Hooks. This extends Hooks beyond individual resource validation, allowing you to run validation checks against entire templates and examine resource relationships. For example, you can now create hooks that validate architectural patterns across multiple resources or enforce team-specific deployment standards. With the change set invocation point, you can automate your change set reviews and reduce the time needed to resolve compliance issues. Refer to the Hooks developer guide to learn more.
Figure 10: CloudFormation’s Hooks for stack and change set target invocation points
Managed hooks for the CloudFormation Guard domain specific language
We introduced the managed hooks to author configuration controls using CloudFormation Guard domain-specific language. This simplifies the hook creation process—you can now write hooks by providing your Guard rule set stored as an S3 object. This is particularly valuable if you’re already using Guard for static template validation, as you can extend these rules to dynamic checks before deployments. To learn more about the Guard hook, check out the AWS DevOps Blog or refer to the Guard Hook User Guide.
Figure 11: CloudFormation Hooks’ Guard language feature
Figure 12: CloudFormation Hooks’ Lambda function feature
CloudFormation Hooks for AWS Cloud Control API target invocation points
Lastly, we extended Hooks to support AWS Cloud Control API (CCAPI) resource configurations. This means your existing resource Hooks can now evaluate configurations from CCAPI create and update operations, allowing you to standardize your proactive control evaluation regardless your IaC tool. If you’re already using pre-built Lambda or Guard hooks, you simply need to specify “Cloud_Control” as a target in your hooks’ configuration to extend their coverage. Learn the detail of this feature from this AWS DevOps Blog. Figure 13: CloudFormation Hooks for AWS Cloud Control API target invocation point
Additional Platform Improvements
StackSets ListStackSetAutoDeploymentTargets API
In March, we enhanced StackSets with the ListStackSetAutoDeploymentTargets API. This new capability gives you better visibility into your auto-deployment configurations by allowing you to list existing target Organizational Units (OUs) and AWS Regions for a given stack set. Instead of logging into individual accounts to understand your deployment scope, you can now get this information in a single API call.
CloudFormation Git sync with request review support
In September, we improved CloudFormation Git sync with pull request workflow support. When you create or update a pull request in a linked repository, CloudFormation automatically posts change set information as PR comments. This integration provides a clear overview of proposed changes within your familiar Git workflow, allowing team members to review infrastructure changes alongside code changes. Visit our user guide and launch blog to learn more.
Figure 14: CloudFormation Git sync with request review support feature
Early 2025 improvements
Reshape your AWS CloudFormation stacks seamlessly with stack refactoring
In February 2025, CloudFormation introduced a new capability called stack refactoring that makes it easy to reorganize cloud resources across your CloudFormation stacks. Stack refactoring enables you to move resources from one stack to another, split monolithic stacks into smaller components, and rename the logical name of resources within a stack. This enables you to adapt your stacks to meet architectural patterns, operational needs, or business requirements. To explore an example scenario, read Introducing AWS CloudFormation Stack Refactoring.
Learn more
Here are some resources to help you get started learning and using CloudFormation to manage your cloud infrastructure:
As we are starting 2025, our focus remains on making infrastructure deployment faster, safer, and more manageable. These enhancements reflect our commitment to solving real customer challenges and improving the CloudFormation experience. We are excited about the roadmap ahead and look forward to bringing you more innovations in 2025.
We encourage you to try these new features and share your feedback. For more detailed information about any of these launches, visit our documentation or check out the AWS DevOps Blog.
The management of configurations across multiple environments and tenants poses a significant challenge in modern software development. Organizations must balance maintaining distinct settings for various environments while accommodating the unique needs of different tenants in multi-tenant architectures. This complexity is compounded by requirements for consistency, version control, security, and efficient troubleshooting.
AWS AppConfig offers a powerful solution to these challenges. AWS AppConfig centrally stores, manages, and deploys application configurations. It streamlines pushing changes without frequent code deployments. The service also enables automatic rollbacks, providing a safety net for configuration changes.
When integrated with a CI/CD pipeline, such as GitLab, AWS AppConfig becomes part of a streamlined, automated system for configuration management. This combination addresses the complexities of multi-environment and multi-tenant deployments, ensuring consistent, version-controlled, and secure configuration management across the entire application ecosystem.
Solution and Scenario Overview
The GitLab CI/CD pipeline in this blog focuses on the way application configurations are managed and deployed using AWS AppConfig. By automating the entire process from configuration updates to multi-environment deployment, it offers a streamlined approach to configuration management.
In this configuration management setup, we’re dealing with a multi-environment, multi-tenant application structure that leverages AWS AppConfig for configuration deployment.
It describes a multi-tenant configuration setup where each tenant has dedicated environments (dev and qa). Real-world examples of what these could represent:
Development (dev): Where developers test new features and changes
Quality Assurance (qa): Where quality assurance teams validate changes before production
The system supports multiple tenants (tenant1, tenant2), each with their own isolated environments. In real-world applications, these tenants could represent:
Different customers:
A retail company (tenant1)
A healthcare provider (tenant2)
Different business units:
North America division (tenant1)
EMEA division (tenant2)
Each tenant maintains separate configurations for their dev and qa environments, with three example configuration files:
AllowList.yml
FeatureFlags.yml
ThrottlingLimits.yml
The ‘template’ directory provides base configuration files that can be inherited and customized by each tenant’s environment-specific configurations. This hierarchical structure ensures that tenants can maintain their unique configurations while adhering to a standardized template format.
Here’s an example of how the template YAML files might look:
The ‘tenants’ directory follows a hierarchical structure where each tenant (tenant1, tenant2) has their own directory. Within each tenant’s directory, there are ‘dev’ and ‘qa’ environment subdirectories. Each environment directory contains three configuration files: AllowList.yml, FeatureFlags.yml, and ThrottlingLimits.yml. These files represent different aspects of the application’s configuration and can override the base templates found in the ‘template’ directory. This structure allows for environment-specific configurations while maintaining a clear separation between tenants and their respective environments.
This structure allows for:
Standardization through templates: The base templates in the ‘template’ directory ensure consistency across all tenants, providing default configurations that can be selectively overridden by tenant-specific needs.
Tenant-specific customization: Each tenant can maintain unique configurations in their dev and qa environments while inheriting from the base templates. This allows for customization without losing standardization benefits.
Environment isolation: Clear separation between dev and qa environments within each tenant’s directory ensures that configuration changes in one environment don’t affect other
Version control of configurations: By storing configurations in a Git repository, changes can be tracked, reviewed, and rolled back if necessary.
AWS AppConfig integration:
Each tenant gets their own Application in AWS AppConfig
Configuration profiles map to different configuration types (AllowList, FeatureFlags, ThrottlingLimits)
Separate environments (dev/qa) within each tenant’s application
The GitLab CI/CD pipeline we’re setting up will need to:
Generate environment and tenant-specific configurations based on these templates
Update the corresponding applications and configuration profiles in AWS AppConfig
Deploy the appropriate configurations to each tenant and environment
Use tags to specify which runner should execute your jobs:
job_name:
tags:
- aws-runner  # Tag of your specific runner
Setting Up the Directory Structure:
First, create the base directory structure using these commands:
# Create directory structure and files
mkdir -p template tenants/{tenant1,tenant2}/{dev,qa}
Create all required YAML files:
for file in AllowList.yml FeatureFlags.yml ThrottlingLimits.yml;do
  touch template/$file
  touch tenants/tenant{1,2}/{dev,qa}/$file
done
Populate the template files:
Copy the content of each YAML file (AllowList.yml, FeatureFlags.yml, ThrottlingLimits.yml) shown above into the corresponding files in the template directory.
For tenant-specific configurations:
Start by copying the template files to each tenant's environment directory
Make sure to replace these variables in both stages (update-app-config and deploy-app-config) of the pipeline. The AWS role should have appropriate permissions to interact with AWS AppConfig service
Here’s the complete .gitlab-ci.yml file:
stages:
- update-app-config
- deploy-app-config
update-app-config:
stage: update-app-config
image:
name: amazon/aws-cli:latest
entrypoint:
- '/usr/bin/env'
script:
- |
# Get list of all tenant
TENANTS=$(find tenants -mindepth 1 -maxdepth 1 -type d -exec basename {} \;)
for TENANT in $TENANTS; do
echo "Processing tenant: $TENANT"
# Create/Get Application for tenant
APP_ID=$(aws appconfig list-applications --query "Items[?Name=='$TENANT'].Id" --output text)
if [ -z "$APP_ID" ]; then
echo "Creating application for tenant '$TENANT'..."
APP_ID=$(aws appconfig create-application --name $TENANT --query Id --output text)
fi
# Process each configuration type
for CONFIG_TYPE in AllowList FeatureFlags ThrottlingLimits; do
echo "Processing config type: $CONFIG_TYPE"
# Create/Get Configuration Profile
PROFILE_ID=$(aws appconfig list-configuration-profiles --application-id "$APP_ID" --query "Items[?Name=='$CONFIG_TYPE'].Id" --output text)
if [ -z "$PROFILE_ID" ]; then
echo "Creating configuration profile '$CONFIG_TYPE' for tenant '$TENANT'..."
PROFILE_ID=$(aws appconfig create-configuration-profile --application-id "$APP_ID" --name "$CONFIG_TYPE" --description "Configuration profile for $CONFIG_TYPE" --location-uri hosted --query Id --output text)
fi
# Process each environment
for ENV in dev qa; do
echo "Processing environment: $ENV"
# Priority: Use tenant-specific config if it exists, otherwise use template
if [ -f "tenants/$TENANT/$ENV/$CONFIG_TYPE.yml" ]; then
echo "Using tenant-specific configuration for $ENV"
CONFIG_CONTENT=$(cat "tenants/$TENANT/$ENV/$CONFIG_TYPE.yml" | base64)
else
echo "Using template configuration for $ENV"
CONFIG_CONTENT=$(cat "template/$CONFIG_TYPE.yml" | base64)
fi
echo "Creating new version for $CONFIG_TYPE configuration in $ENV..."
aws appconfig create-hosted-configuration-version \
--application-id "$APP_ID" \
--configuration-profile-id "$PROFILE_ID" \
--content "$CONFIG_CONTENT" \
--content-type "application/json" \
configuration_version_output
done
done
done
variables:
  AWS_CREDS_TARGET_ROLE: arn:aws:iam::<aws_account_ID>:role/GitLab
  AWS_DEFAULT_REGION: <aws_region>
deploy-app-config:
stage: deploy-app-config
image:
name: amazon/aws-cli:latest
entrypoint:
- '/usr/bin/env'
script:
- yum install -y jq
- |
TENANTS=$(find tenants -mindepth 1 -maxdepth 1 -type d -exec basename {} \;)
for TENANT in $TENANTS; do
echo "Processing tenant: $TENANT"
APP_ID=$(aws appconfig list-applications --query "Items[?Name=='$TENANT'].Id" --output text)
# Process each environment
for ENV in dev qa; do
echo "Processing environment: $ENV"
# Create/Get Environment
ENV_ID=$(aws appconfig list-environments --application-id "$APP_ID" --query "Items[?Name=='$ENV'].Id" --output text)
if [ -z "$ENV_ID" ]; then
echo "Creating environment '$ENV' for tenant '$TENANT'..."
ENV_ID=$(aws appconfig create-environment --application-id "$APP_ID" --name "$ENV" --description "Environment for $ENV" --query Id --output text)
fi
# Process each configuration types
for CONFIG_TYPE in AllowList FeatureFlags ThrottlingLimits; do
echo "Processing $CONFIG_TYPE for $TENANT/$ENV"
PROFILE_ID=$(aws appconfig list-configuration-profiles --application-id "$APP_ID" --query "Items[?Name=='$CONFIG_TYPE'].Id" --output text)
echo " Profile ID $PROFILE_ID "
# Get latest version for this specific profile
LATEST_VERSION=$(aws appconfig list-hosted-configuration-versions \
--application-id "$APP_ID" \
--configuration-profile-id "$PROFILE_ID" \
--query "Items[0].VersionNumber" \
--output text)
# Get current deployment for this specific profile
CURRENT_DEPLOYMENT=$(aws appconfig list-deployments \
--application-id "$APP_ID" \
--environment-id "$ENV_ID" \
--query "Items[?ConfigurationName=='$CONFIG_TYPE'].ConfigurationVersion | [0]" \
--output text)
echo "Current deployment $CURRENT_DEPLOYMENT"
CURRENT_VERSION=$(aws appconfig list-deployments \
--application-id "$APP_ID" \
--environment-id "$ENV_ID" \
--query "Items[?ConfigurationName=='$CONFIG_TYPE'].ConfigurationVersion | [0]" \
--output text)
echo "Latest Version: $LATEST_VERSION"
echo "Current Version: $CURRENT_VERSION"
if [[ "$CURRENT_DEPLOYMENT" == "None" ]] || [[ "$LATEST_VERSION" != "$CURRENT_VERSION" ]]; then
echo "Starting deployment for $TENANT/$ENV/$CONFIG_TYPE..."
DEPLOYMENT_RESPONSE=$(aws appconfig start-deployment \
--application-id "$APP_ID" \
--environment-id "$ENV_ID" \
--deployment-strategy-id Linear50PercentEvery30Seconds \
--configuration-profile-id "$PROFILE_ID" \
--configuration-version "$LATEST_VERSION")
DEPLOYMENT_ID=$(echo $DEPLOYMENT_RESPONSE | jq -r '.DeploymentNumber')
# Monitor deployment
max_attempts=10
attempt=1
while [ $attempt -le $max_attempts ]; do
echo "Checking deployment status (attempt $attempt of $max_attempts)..."
status=$(aws appconfig get-deployment \
--application-id "$APP_ID" \
--environment-id "$ENV_ID" \
--deployment-number "$DEPLOYMENT_ID" \
--query "State" \
--output text)
if [ "$status" = "COMPLETE" ]; then
echo "Deployment completed successfully!"
break
elif [ "$status" = "FAILED" ] || [ "$status" = "ROLLED_BACK" ]; then
echo "Deployment failed or was rolled back!"
exit 1
fi
if [ $attempt -eq $max_attempts ]; then
echo "Deployment timed out after $max_attempts attempts"
exit 1
fi
attempt=$((attempt + 1))
sleep 30
done
else
echo "No changes detected for $TENANT/$ENV/$CONFIG_TYPE (Current: $CURRENT_VERSION, Latest: $LATEST_VERSION). Skipping deployment..."
fi
done
done
done
dependencies:
- update-app-config
variables:
AWS_CREDS_TARGET_ROLE: arn:aws:iam::<aws_account_ID>:role/GitLab
AWS_DEFAULT_REGION: <aws_region>
Implementing Pipeline Stages
Update-App-Config Stage:
Creates/Updates AWS AppConfig Applications:
Creates one application per tenant (tenant1, tenant2)
Uses tenant ID as application name
Retrieves existing application if already present
Manages Configuration Profiles:
Creates three profiles per tenant application (AllowList, FeatureFlags, ThrottlingLimits)
Each profile represents a distinct configuration type
Handles profile creation if not already existing
Creates Hosted Configuration Versions:
Processes changes from both template and tenant directories
Prioritizes tenant-specific configurations over templates
Creates new versions only for modified configurations
Uploads properly encoded configurations to AWS AppConfig
Deploy-App-Config Stage:
Environment Deployment:
Manages dev and qa environments per tenant
Creates environments if not existing
Uses staged deployment strategy
Tenant Configuration Process:
Deploys per tenant and configuration type
Checks current deployed version against latest version
Only deploys if either of the follows is true:
No existing deployment is found
Latest Hosted Configuration version differs from currently deployed version
Maintains tenant-specific settings and version history
Provides clear deployment status messages, including cases where deployment is skipped
Deployment Management:
Executes AWS AppConfig deployments
Monitors deployment status
Handles failures and rollbacks
Times out after 10 retries
Executing the Pipeline
Initiation:
Pipeline triggered by changes pushed to the repository
Update-App-Config Stage:
Creates or updates applications and configuration profiles
Generates new versions of hosted configurations
Deploy-App-Config Stage:
Iterates through each environment tenant and their environments
Checks current deployment status for each environment and tenant
Initiates new deployments only for changed configurations
Note: Deployment Strategy used in this example is a fast one used for testing (Linear50PercentEvery30Seconds) but for real production workloads, the reader should use the slower, AWS-recommended Linear20PercentEvery6Minutes strategy. More details here
This structured execution process ensures efficient and consistent deployment of configuration changes across the entire application ecosystem, maintaining synchronization between GitLab and AWS AppConfig.
Cleaning up
To clean up all AWS AppConfig resources created by this solution, you can use the following cleanup script. Create a file named delete_appconfig_resources.sh with this content:
#!/bin/bash

# List all applications
APPS=$(aws appconfig list-applications --query 'Items[*].Id' --output text)

for APP_ID in $APPS
do
  echo "Processing application $APP_ID"

  # List and delete all environments for this application
  ENVS=$(aws appconfig list-environments --application-id $APP_ID --query 'Items[*].Id' --output text)
  for ENV_ID in $ENVS
  do
    echo "  Deleting environment $ENV_ID"
    aws appconfig delete-environment --application-id $APP_ID --environment-id $ENV_ID
  done

  # List and delete all configuration profiles for this application
  PROFILES=$(aws appconfig list-configuration-profiles --application-id $APP_ID --query 'Items[*].Id' --output text)
  for PROFILE_ID in $PROFILES
  do
    echo "  Deleting configuration profile $PROFILE_ID"

    # Delete all hosted configuration versions for this profile
    VERSIONS=$(aws appconfig list-hosted-configuration-versions --application-id $APP_ID --configuration-profile-id $PROFILE_ID --query 'Items[*].VersionNumber' --output text)
    for VERSION in $VERSIONS
    do
      echo "    Deleting hosted configuration version $VERSION"
      aws appconfig delete-hosted-configuration-version --application-id $APP_ID --configuration-profile-id $PROFILE_ID --version-number $VERSION
    done

    # Delete the configuration profile
    aws appconfig delete-configuration-profile --application-id $APP_ID --configuration-profile-id $PROFILE_ID
  done

  # Delete the application
  echo "  Deleting application $APP_ID"
  aws appconfig delete-application --application-id $APP_ID
done

echo "All AppConfig resources have been deleted."
The script is a comprehensive cleanup utility for AWS AppConfig resources.
To execute this script, you need to have the AWS CLI installed and configured with appropriate credentials that have permissions to delete AppConfig resources. Make the script delete_appconfig_resources.sh executable by running the command:
chmod +x cleanup_appconfig.sh.
Before running the script, ensure that you’re in the correct AWS account and region, as this script will delete ALL AppConfig resources in the configured account and region. To execute the script, simply run it from your terminal: ./ delete_appconfig_resources.sh
It’s crucial to note that this script performs irreversible deletions. Use it with extreme caution, preferably in non-production environments or when you’re absolutely certain you want to remove all AppConfig resources.
Conclusion
This blog post has explored the powerful synergy between GitLab CI/CD and AWS AppConfig for managing application configurations in multi-tenant environments. We’ve demonstrated how this integration automates and streamlines the process of updating, versioning, and deploying configuration changes, offering benefits such as scalability, version control, and the balance between consistency and flexibility. By adopting this approach, development teams can significantly reduce manual errors, save time, and focus more on building features, ultimately leading to faster development cycles and more reliable applications in our increasingly complex and distributed computing landscape.
Operators, administrators, developers, and many other personas leveraging AWS come across multiple use cases and common issues such as lack of permissions, bugs in code in AWS Lambda, and more when leveraging the AWS console. To help alleviate this burden when using the console, AWS released Amazon Q to assist with users accessing the console with these use cases. Amazon Q is AWS’s generative AI-powered assistant that helps write code, answer questions, generate content, solve problems, manage AWS resources, and take actions. A component of Amazon Q is Amazon Q Developer. One way to interact with the service is to chat with Amazon Q Developer in the AWS Management Console, the AWS Console Mobile Application, on AWS websites, AWS Documentation websites, and chat channels integrated with AWS Chatbot to learn about AWS services. You can ask Q Developer about best practices, recommendations, step-by-step instructions for AWS tasks, and architecting your AWS resources and workflows.
In this blog post, we will highlight best practices for interacting with Q Developer in the console including topics such as using Q Developer in the console to generate code snippets, architect workloads, and understand your costs.
Prerequisites
To follow along with these examples, the following prerequisites are required:
Please Note – Amazon Q in Console may generate different output than shown in examples below due to its non-deterministic nature.
To start, access the Amazon Q Developer service by signing into the AWS console and clicking the Amazon Q icon on the right-hand panel as shown below in Figure 1. Authenticate if necessary:
Figure 1: Accessing Amazon Q Chat
Use Q to learn about AWS services and best practices
In this section, we will look at how Amazon Q can help you learn about AWS services and also outline the best practices for using those services
Learn about services available in AWS
Whether someone is just learning or an experienced user, Amazon Q provides a simple way to discover AWS capabilities and get helpful information whenever needed. For example, if you are looking to learn on how to auto-scale your compute instances based on a metric you can ask Amazon Q in console.
Sample prompt – I need to set a autoscaling group for EC2 instances with this requirement, if CPU utilization goes above 50% for 5 minutes then it should add new instance and if CPU utilization drops below 50% for 5 minutes then it should delete 1 instance.
Figure 2: User Prompt and Response from Amazon Q for Auto Scaling Compute Instance based on a specific metric and threshold
The response from Amazon Q lists down all the steps to set an Auto Scaling Group based on the requirements provided in the prompt.
Ask specific questions about AWS services
Amazon Q in console can also help you to run systems to deliver business value keeping best practices in mind. With natural language prompts, you can learn the best practices when using AWS services.
Sample Prompt –
I am using API Gateway for REST APIs. I have configured timeout for requests. I would like to learn additional best practices to reduce and handle long running requests.
Figure 3: User Prompt and Response from Amazon Q keeping compute costs low
As shown above in Figure 3, Amazon Q then summarizes various ways to optimize for long running requests in Amazon API Gateway, for example, implement timeouts, use asynchronous invocation for long running operation if possible and several other ways to optimize.
Use Q to generate code snippets or scripts to automate tasks using AWS SDK or AWS CLI
Developers or System Administrators can use Q to generate code snippets or scripts to automate tasks instead of spending time going through documentation.
How to write an AWS Lambda function to read data from S3
For example, a developer may way to get started writing an AWS Lambda function that reads data from an Amazon S3 bucket but doesn’t know how to get started, Amazon Q can help.
Figure 4: User Prompt and Response from Amazon Q on instructions to write a Lambda function
Figure 5: Response from Amazon Q with sample code to write a Lambda function
As shown above in Figure 4 & 5, Amazon Q returns step-by-step instructions on how to write the Lambda function, including sample code for reference.
How do I upload a file to an S3 bucket using the AWS CLI?
If a developer or IT Professional uses the AWS CLI frequently but struggle with finding right commands to accomplish a task, then Amazon Q is definitely helpful
Sample Prompt –
How do I upload a file to an S3 bucket using the AWS CLI?
Figure 6: User Prompt and Response from Q with CLI command to upload file to S3 bucket
As shown above in Figure 6, Amazon Q returns the CLI command to upload a file to an S3 bucket. The response also suggests the command to verify the upload.
Use Console-to-Code to write code to automate use of other services
Console-to-Code records your console actions, then uses generative AI to suggest code in your preferred language which currently supports CLI commands, CDK Java, CDK Python, CDK TypeScript, CloudFormation JSON/YAML.
Let’s say a developer wants to generate a CloudFormation YAML with an Amazon EC2 instance and Amazon RDS database instance. For this, the developer can go to the console of Amazon EC2 and Amazon RDS. On the right side, choose Console-to-Code icon and choose Start Recording.
As shown in the figures below, once an Amazon EC2 instance and then Amazon RDS DB instance is launched, stop the recording and simply download the CloudFormation YAML template.
Figure 8: Generate Infrastructure-As-Code from the Console-to-Code recording
Figure 9: Generated CloudFormation YAML template from the Console-to-Code recording
Use Q to architect a workload & optimize
In this section, we will focus on leveraging Amazon Q to architect new workloads and optimize existing workloads.
Architecting Workloads
Now, a developer wants to build a new financial services application with the following requirements:
Architecture must be serverless & event driven
It must provide functionality as deposits and withdrawals
It should use low-cost, efficient AWS services.
It should scale with traffic spikes that can reach thousands of requests per second.
Should support REST APIs
Let’s prompt Amazon Q Developer by copying the following prompt below and pasting it into the chat window:
Sample Prompt:
How can I build a new financial services application with the following requirements: it should be serverless and event driven, must provide functionality as deposits and withdrawals, It should use low-cost efficient AWS services, It should scale with traffic spikes that can reach thousands of requests per second, and lastly it should support REST APIs.
Amazon Q should provide a response on how to architect this workload. Here is a sample response received from Amazon Q:
Figure 10: Response from Amazon Q for architecture
Amazon Q was able to provide the following response in full:
________________________________________________
To build a new financial services application with the requirements you described, I would recommend the following AWS services and architecture:
Serverless and Event-Driven Architecture:
Use AWS Lambda for the core application logic, which will allow you to run your code without provisioning or managing servers. Integrate AWS Lambda with other serverless services like Amazon API Gateway for the REST API, Amazon DynamoDB for the database, and Amazon SNS/SQS for event-driven messaging.
Deposits and Withdrawals Functionality:
Use Amazon DynamoDB as the database to store customer account information and transaction details.
Implement the deposit and withdrawal logic in AWS Lambda functions, which can be triggered by events from Amazon API Gateway or Amazon SNS/SQS.
Low-Cost and Efficient AWS Services:
Leverage AWS Lambda, which charges only for the compute time you consume, and Amazon DynamoDB, which provides a pay-per-request pricing model.
Use Amazon API Gateway’s pay-per-call pricing to keep costs low for the REST API.
Consider using Amazon SQS and Amazon SNS for their low-cost, highly available, and scalable messaging capabilities.
Scalability and High-Performance:
AWS Lambda and the other serverless services you choose will automatically scale to handle traffic spikes of thousands of requests per second.
You can further optimize performance by using features like Amazon API Gateway’s caching, Amazon DynamoDB’s auto-scaling, and Amazon SQS’s message batching.
REST API Support:
Integrate your application logic in AWS Lambda with Amazon API Gateway to expose a RESTful API. Amazon API Gateway will handle the API management, including routing, authentication, and throttling.
To get started, I recommend reviewing the following AWS documentation:
As shown above, Amazon Q was able to provide the service recommendations for our architecture based on the requirements provided along with links to services recommended based on the requirements
Optimizing workloads
Now, let’s a developer or IT professional has an architecture that revolves around Amazon EC2 and an instance deployed called Server-1-demo in AWS and wants to optimize to help save on costs.
Similar to the previous section, open a new chat window within the Amazon Q chat in the console and enter the following prompt:
Sample Prompt:
Based on the current CPU utilization of my EC2 Server-1-demo, what do you recommend I do to cost optimize?
As a result, Q provides the following response:
Figure 11: Optimization Response from Amazon Q
As shown, Amazon Q took in the context of the CPU utilization for Server-1-demo and made recommendations to leverage new instance types such as AWS Graviton which is designed to deliver the best price performance for your cloud workloads running in Amazon Elastic Compute Cloud (Amazon EC2) along with other recommendations.
Use Q to understand your costs
Another way to leverage Q in the console is to analyze costs. A developer or IT professional can use Amazon Q, to retrieve and analyze cost data from AWS Cost Explorer, being able ask questions about AWS costs and receive answers in natural language that reflect the actual costs of your AWS account.
Now, open a new Amazon Q in Console chat window and lets try the following prompt as an example:
Sample Prompt:
Show me the breakdown of EC2 costs by instance type for the last 30 days.
Figure 12: Response from Amazon Q for the breakdown of EC2 costs in the last month
As shown above in Figure 12, Q Developer provides a detailed breakdown of the EC2 instance types for the last 30 days.
Now, trying another example:
Sample Prompt:
What was my cost breakdown by service for the past three months?
Figure 13: Response from Amazon Q for last 3 months spend analysis
As shown in figure 13, Amazon Q provides detailed cost breakdowns, including percentages of total spend, making it easy to understand your AWS usage and expenses. This feature allows you to quickly identify your highest-cost services and track spending trends over time. Always verify your cost data with AWS Cost Explorer for the most accurate information. For more details and information on this capability, check out this blog covering the feature in more detail.
Best practices for using Amazon Q in the console
The previous sections showcased examples of leveraging Amazon Q capabilities for AWS application architecture and account management. In both cases, the input given to Amazon Q directly affects its output quality. Your question should be concise, clear and contain the necessary details for the tool to understand the scenario and what should be answered. The recommended approach for providing effective input to a generative AI chat bot is called Prompt Engineering. By adhering to the following best practices, you can achieve improved outcomes when using Amazon Q:
Specify the task you want Q to do: explain a concept, compare services, list pros and cons, generate a CLI command, generate a code snippet, suggest architecture options for a scenario.
Provide context: Why do you need to know this concept? For which part of your application or architecture will you apply the knowledge?
Figure 14: Amazon Q asks for additional details to better answer the question.
In this example, we asked for scenarios, which is what type of answer we want. We also specified the service we want scenarios about, and the edge case of the scenario (after instance creation). Amazon Q summarized our question and provided scenarios and sources in accordance with what we asked.
Break a series of questions into multiple questions.
Ask for one task at a time.
Don’t stop at the first answer; keep asking questions that use the information to help Q provide more enriched responses.
Figure 15: Amazon Q uses chat context to give an answer.
In this scenario, the provided input was not enough for Q to provide a good answer, so it asked for more details and considered both inputs as a context to the answer.
Be mindful about security related questions about your account- Amazon Q in console may not provide answers that address security in your account
Your input must have the maximum of 1000 characters. This is another reason to be concise while providing an input.
Create a new conversation if you are going to start a new topic discussion. Unnecessary context will reduce Q answers specificity to your new situation.
Figure 16: Amazon Q does not provide security tips. Create a new conversation. Maximum allowed characters are 1000.
Conclusion
In this blog post, we explored the various ways in which Amazon Q, AWS’s generative AI-powered assistant, is used in the AWS Console to enhance productivity and reduce ramp-up time for developers, DevOps engineers, and architects. Amazon Q functions as an AWS consultant, offering advice on various tasks, such as understanding AWS services and implementing best practices, as well as generating code snippets and automating CLI commands. The tool’s capability to help architect new workloads and enhance existing ones based on specific needs was demonstrated with detailed examples. The importance of prompt engineering – crafting clear, concise prompts to elicit high-quality responses from the AI assistant – was also discussed. By embracing the capabilities of Amazon Q in the console, AWS users will streamline their workflows and speed up their cloud journey. Whether you’re a seasoned cloud architect or starting out, this AI-powered assistant will serve as a partner, helping you navigate the AWS landscape and unlock new levels of efficiency. As you continue exploring the possibilities of Amazon Q, follow the best practices outlined in this post, experiment!
As your cloud infrastructure grows and evolves, you may find the need to reorganize your AWS CloudFormation stacks for better management, for improved modularity, or to align with changing business requirements. CloudFormation now offers a powerful feature that allows you to move resources between stacks. In this post, we’ll explore the process of stack refactoring and how it can help you maintain a well-organized and efficient cloud infrastructure.
Understanding Stack Refactoring
Stack refactoring is the process of restructuring your CloudFormation stacks by moving resources from one stack to another or renaming a resource with a new logical ID within the same stack. This capability is particularly useful when you want to:
Split a large, monolithic stack into smaller, more manageable stacks
Reorganize resources to better align with your application architecture or organizational structure
Rename the logical IDs of resources to make templates more readable
Example Scenario
To demonstrate this capability, you are going to create a stack and then move some of its resources into a new stack. You will evaluate the new CLI commands that you need to leverage to make this possible. For this example, you are going to have an SNS topic with a lambda function subscribed to your SNS topic. As your usage of the SNS topic expands, you want to break apart the subscriptions into a different stack.
Create a new template called before.yaml with your starting template:
Create a new template called afterSns.yaml with the content below. This template has your SNS topic in it and has a new export in it that will export the SNS topic ARN. This export will be used by your other templates to get the required SNS topic ARN.
Create a new template called afterLambda.yaml with the content below. This template includes all the resources to create a Lambda subscription to your SNS topic. This template switched the !Ref Topic to use the exported valued by using !ImportValue TopicArn.
Create a resource mappings file called refactor.json to rename the logical ID of a resource. This file defines the source and destination stack names and logical IDs for resources being refactored. If the logical IDs don’t change, this file doesn’t need to be specified.
Create a stack refactor task. You are using enable-stack-creation to tell the refactoring capability to create the destination stack for us. If the destination stack already exists you don’t have to provide this option.
Stack refactoring in AWS CloudFormation represents a significant advancement in infrastructure management, offering a safer and more efficient way to reorganize your cloud resources without disruption. This feature eliminates the traditional need to remove the resource, with a retain policy, and then import the resource when restructuring stacks, helping you reduce misconfiguration risk and save time. Through the example demonstrated in this post, you’ve seen how to split a monolithic stack into smaller, focused stacks while using exports and imports to maintain dependencies between stacks. You’ve also explored the new CloudFormation CLI commands that make stack refactoring possible while maintaining resource stability during reorganization.
As your infrastructure evolves, stack refactoring provides the flexibility needed to adapt your CloudFormation stack organization to changing requirements while maintaining the integrity of your cloud resources. This capability is particularly valuable for teams looking to improve their infrastructure maintainability and align their resource organization with evolving architectural patterns. Remember to thoroughly test your refactoring plans in a non-production environment first, and always ensure your new stack structure maintains the necessary security and access controls.
Developers, IT Operators, and in some cases, Site Reliability Engineers (SREs) are responsible for deploying and operating infrastructure and applications, as well as responding to and resolving incidents effectively and in a timely manner. Effective incident management requires quick diagnosis, root cause analysis, and implementation of corrective actions. Diagnosing the root cause can be challenging in the context of modern systems that involve multiple resources deployed across distributed environments. Amazon Q Developer, a generative AI-powered assistant, can help simplify this process by diagnosing errors you receive in the AWS Management Console.
Amazon Q Developer can save you critical time when dealing with production issues by helping to diagnose errors related to your AWS environment. These errors could be the result of potential misconfiguration across multiple resources, and usually requires you to navigate between several service consoles to identify the root cause. Amazon Q Developer applies machine learning models to automate diagnosis of errors that arise in the AWS Console interface. This reduces the mean time to repair (MTTR) and minimizes the impact of incidents on business operations.
This blog post explores the Amazon Q Developer feature to diagnose errors in AWS Console while working with AWS services. We describe how this feature works in order to provide you guidance on troubleshooting. We take a look behind-the-scenes to show the processes that power this feature.
Diagnose with Amazon Q
The Diagnose with Amazon Q feature is activated when an error occurs in the console for an AWS service that is currently supported by this functionality, and a user with appropriate permissions clicks the Diagnose with Amazon Q button next to the error message. Amazon Q provides a natural language explanation that analyzes the root cause of the error. With a second click on Help me resolve, Amazon Q displays an ordered list of instructions which can be used to resolve the error condition. Once completed, you can provide feedback on whether the resolution provided by Amazon Q was helpful.
To make things concrete, we consider two running examples.
Example 1: Assume that you try to delete an S3 bucket which is not empty. This results in an error message:
This bucket is not empty. Buckets must be empty before they can be deleted. To delete all objects in the bucket, use the empty bucket configuration.
Example 2: Suppose that you try to list objects in a particular S3 bucket, but lack IAM permissions to do so. This results in an error message:
Insufficient permissions to list objects. After you or your AWS administrator has updated your permissions to allow the s3:ListBucketaction, refresh the page. Learn more about Identity and access management in Amazon S3.
Diagnose with Amazon Q IAM permissions related to EC2 instance launch error
Behind the Scenes: How Amazon Q generates a diagnosis
When you click on Diagnose with Amazon Q button next to the error message in the AWS Management Console, Amazon Q generates an Analysis that expresses the root cause of the error in natural language. This step is assisted by Large Language Models (LLMs) and is based on context information only. The context provided to the LLM includes the error message shown in the console, the URL of the triggering action, and the IAM role of the user signed in the AWS Console. The service always operates within the permissions granted by your role as you operate in the AWS Console, ensuring that privileges are never escalated beyond what are assigned to you.
When you click on Help me resolve button after you have reviewed the analysis, Amazon Q retrieves additional information about the state of the resources in the AWS Account where the error occurred. This is accomplished by interrogating the customer account in various ways. In this phase, the system actively decides which information is still missing and issues interrogation requests against internal services to fulfil the information need. Interrogation is not needed for simple errors, such as Example 1 above, but becomes essential in order to resolve more complex errors, where information from the context proves insufficient.
Given the context, error analysis, user permissions, and results of account interrogation, Amazon Q generates step-by-step Resolution instructions. This step is assisted by LLMs.
After implementing and validating the steps provided by Amazon Q to resolve the error in the console, you have the option to provide feedback of your experience.
Diagram showing Interactions between User, AWS Console and Amazon Q Developer
Context Information
Contextual information helps the LLMs to generate more relevant and informed outputs. Context is provided to Amazon Q as input from the console automatically. As the basis for all further analysis and decisions, it should be as rich as possible. At a minimum, Amazon Q obtains the error message, the URL for the triggering action, and the IAM role that the signed-in user assumes. The system automatically extracts relevant identifiers from the context. In our running Example 1, the URL may be https://s3.console.aws.amazon.com/s3/bucket/my-bucket-123456/delete?region=us-west-2, from which Amazon Q extracts aws_region = "us-west-2" and s3_bucket_name = "my-bucket-123456".
Beyond this minimum context, Amazon Q can obtain additional information from the console, pertaining to what the user sees on the screen when the error happens, such as content of text fields or widgets in the current UI. Amazon Q can also make use of specific context provided by the underlying service. In the case of Example 2 above, the bucket name is extracted from the URL, the action s3:ListBucket from the error message, and Amazon Q may obtain additional information from IAM about related policies and accept or deny statements.
Interrogating the signed-in user’s Account
Diagnose with Amazon Q functionality is not just a passive receiver of context information, it has built-in capabilities of actively asking for additional information. This includes developing an understanding of resources in the AWS account, and their relationship with the resource experiencing the error. Such interrogation queries are planned by a subsystem based on context information. It provides a low-latency and deterministic approach to find resources and their relationships. This relationship context provided to the LLM, such as EBS volumes attached to an EC2 instance or policies included in the attached IAM role, improves the accuracy of root cause analysis for diagnosing the error.
In the simple running Example 1 where error is due to non-empty S3 bucket, the error message and the console URL contain all the necessary information to proceed, and active interrogation is not required. On the other hand, for the IAM permission error in Example 2, it’s helpful to understand the permissions on the IAM role associated with the resource experiencing the error. Amazon Q can fetch identity-level policies for the role and resource-level policies for the affected resource, based on which it can diagnose the cause of the error, using internal IAM services. To be concrete, the URL for Example 2 may be https://s3.console.aws.amazon.com/s3/buckets/my-bucket-123456?region=us-west-2&bucketType=general&tab=objects, from which Amazon Q extracts region and S3 bucket name. It can also extract the action s3:ListBucket from the error message itself. Based on this information, Amazon Q can fetch bucket policies for my-bucket-123456, identity-level policies for the role, then scan those for presence or absence of the s3:ListBucket action, or call internal IAM services to provide additional information about the cause of access being denied.
This subsystem uses AWS Cloud Control API (CCAPI) which is called on your behalf by Amazon Q with the permissions granted by your IAM Role. As part of onboarding to Amazon Q, the AmazonQFullAccess managed policy is attached to the Role that can access Amazon Q. This managed policy contains the ListResources and GetResource CCAPI IAM permissions. This ensures all Roles given that managed policy will have access to the CCAPI read and list endpoints. If you do not attach the AmazonQFullAccess managed policy to the required roles, you will need to attach the ListResources and GetResource permission directly to the role.
Generating Step-by-step Resolution Instructions
At this point, all acquired information is synthesized by Amazon Q in order to generate useful and actionable resolution instructions. As an illustration, possible sample instructions for the running examples under consideration are listed below. As the models are updated and improved over time, the responses can change.
For Example 1, sample instructions could look like:
Navigate to the S3 console, click “Buckets”, and select the my-bucket-123456 bucket
Click on the “Empty” tab.
If your bucket contains a large number of objects, creating a lifecycle rule to delete all objects in the bucket might be a more efficient way of emptying your bucket
Type “permanently delete” in text input field and confirm that all objects are to be removed.
Retry deleting the my-bucket-123456 S3 bucket.
For Example 2, you may obtain:
Go to the IAM console. Edit the IAM policy attached to the role ReadOnly
Allow for the s3:ListBucket action for resource being the S3 bucket ARN arn:aws:s3:::my-bucket-123456.
Save the updated IAM policy
Refresh the S3 console page to list the objects in the bucket my-bucket-123456
Note that the instructions contain information inferred from the context, such as bucket name my-bucket-123456, instead of placeholders. Instructions returned by Diagnose with Amazon Q are complete and fine-grained enough in order to be followed without any extra effort. In fact, while the service makes use of an LLM to synthesize resolution instructions, Amazon Q uses post-processing to correct frequently occurring mistakes. For example, in Example 2 above, the LLM may have returned the ARN as arn:aws:s3:<region>::<bucket_name>, which would be corrected to what is shown above.
The instructions returned for Example 2 above assume that the reason for the user not being able to list objects is a missing Allow statement in the policies attached to the ReadOnly role. Other root causes could be a Deny statement in a policy attached to the S3 bucket, or to the ReadOnly role. Diagnose with Amazon Q can use account interrogation in order to identify the correct root cause and propose the right resolution. In the example above, it can fetch the policies attached to the ReadOnly role and check whether s3:ListBucket is missing indeed, or fetch policies attached to the bucket bucket-123456.
Validation
One goal for Diagnose with Amazon Q is to attain wide coverage of AWS rapidly, while keeping the quality bar high, so that you obtain useful, actionable advice where ever you obtain an error. An important prerequisite to attain this goal is a robust and flexible evaluation system. Evaluating systems based on Generative AI is challenging due to the large output space (natural language) and non-deterministic behavior.
In a nutshell, our validation system is based on building a large dataset of errors, where each record has a certain number of annotations. Each record contains the context (templatized error message and console URL; meaning that bucket-123456 is replaced by {{s3_bucket_name}}, us-west-2 by {{aws_region}}). Annotations include Infrastructure as Code (CloudFormation) descriptions of the erroneous account state and the triggering action, as well as ground truth responses obtained from expert annotators. These records allow us to simulate the behaviour of variants of our system without human interactions and many times faster than real time (by way of parallelization). We are also developing automated validation metrics for comparing ground truth annotations and system responses, based on which offline evaluations can be run fully automatically.
This validation system allows us to rapidly validate new ideas by comparing them against the current state, while also guarding against regressions. While human experts are still needed to provide annotations of error records, we actively innovate to speed up and simplify these tasks, by building annotation tools which avoid natural language input, have validations built in, and are rather asking to correct system output than providing ground truth annotations from scratch.
Conclusion
The Diagnose with Amazon Q feature of Amazon Q Developer allows you to determine the cause of an error in the AWS Console without needing to navigate to multiple service consoles. By providing tailored, step-by-step instructions specific to your AWS account and error context, Amazon Q Developer empowers you to troubleshoot and resolve issues efficiently. This helps your organization achieve greater operational efficiency, reduce downtime, improve service quality, and free up valuable human resources enabling them to focus on higher-value activities. We also provide you details on how AI and machine learning capabilities work behind the scenes to enable this functionality.
This post is co-written with Dr. Geoff Ryder, Manager, at SmugMug.
Introduction
SmugMug operates two very large online photo platforms: SmugMug and Flickr. These platforms enable more than 100 million customers to safely store, search, share, and sell tens of billions of photos every day. However, the data science and engineering team at SmugMug and Flickr often faces complex data modeling challenges that require significant time to resolve.
These challenges arise due to several factors. First, the team has to contend with diverse datasets from different sources. Additionally, the database schema and tables are highly complex, and the team needs to quickly understand application (PHP) code and database table structures in order to generate the necessary complex database queries. Specifically, SmugMug uses Amazon Redshift as its cloud data warehouse to analyze patterns in petabyte-scale data stored in Amazon S3, as well as transactional data in Amazon Aurora and Amazon DynamoDB. This allows them to generate dozens of business reports daily.
However, the complexity increases further as many database tables also need to be imported from third-party organizations into Amazon Redshift, where they are joined with SmugMug and Flickr’s internal tables. In extreme cases, properly modeling all these database tables and handling issues like granularity, cardinality, timestamps and missing data could take years – an impractical timeline for the business. We are excited to walk through SmugMug’s data modeling use cases and how SmugMug uses Amazon Q Developer to improve the data science and engineering team’s productivity.
Discovering Amazon Q Developer
SmugMug was one of the first customers to pilot Amazon Q Developer (previously Amazon CodeWhisperer), the most capable AI-powered assistant for software development that re-imagines the experience across the entire software development lifecycle, making it easier and faster to build, secure, manage, optimize, operate, and transform applications on AWS. There are multiple Amazon Q Developer use cases at SmugMug and Flickr, such as using Amazon Q Developer agent (/dev) for software development (i.e. generating implementation plans and the accompanying code), generating inline code suggestions, asking Amazon Q Developer in chat about AWS services and best practices, and analyzing AWS usage and costs for Cloud Financial Management (CFM) needs. For the data science and engineering team specifically, the key feature is chatting with Amazon Q Developer in integrated development environments (IDEs) like Intellij DataGrip. The data analysts and data scientists at SmugMug and Flickr ask questions in Amazon Q Developer chat to analyze database schemas, generate data model diagrams from DDL (Data Definition Language) statements, convert queries between languages, automatically generate complex database queries for data analysis, generate code to validate table contents, and predict trends using ML (Machine Learning).
Implementing Amazon Q Developer
To solve the data modeling challenges SmugMug faced, the team collaborated closely with their AWS Account Team, AWS Professional Services, and the Amazon Q Developer service team to create and test a data modeling assistant solution using Amazon Q Developer.
As a first step, the data modeler needs to bring the right metadata to bear. For simpler cases, the commands “show view myschema.v” or “show table myschema.t“ retrieve DDL schema information about the specified view or table from Amazon Redshift into the IDE console.
Here’s an example using simulated data for a hypothetical company. For this typical company that handles orders for products, the result of typing “show table sample.orderinfo” and “show table sample.skuinfo”might be:
This DDL text is now in the open tab. By selecting the text to highlight it, that DDL text becomes part of the context that Amazon Q Developer sees. The modeler can start asking questions about them in the Amazon Q Developer chat window in the IDE.
In complex scenarios, establishing the correct modeling context requires a combination of schema information, legacy SQL, application source code in various programming languages, sample values, and natural language documentation. Amazon Q Developer addresses this by creating a local index of relevant files and content. When a question is asked using @workspace, this index is consulted to identify and include pertinent sections of code and information in the request. (See this article for additional details on workspace). The prompt plays a crucial role in measuring similarity, so providing comprehensive context within it is essential. To optimize this process, the IDE settings feature a tunable workspace index function, allowing for enhanced performance in identifying and incorporating relevant context.
Workspace Index Settings
By adopting Amazon Q Developer as a team, we are able to jointly develop and share proprietary prompt text to address the four steps in our modeling process, as follows.
Step 1. Define the goal for the data modeling project
From prior knowledge, sketch a high-level goal for a data model. Gather the data for it manually, or by e.g. querying a vector database and adding its documents to the project.
For this example, we choose as the goal to compute aggregated metrics from a new table or view composed of two existing tables, sample.orderinfo and sample.skuinfo. These contain simulated data about product sales that are common to many companies. The order table is in the style of a fact table that logs customer orders, and the stock keeping unit (SKU) table is a dimension table that provides additional data points of interest about each order. The order and SKU information need to be combined by a join operation before we can compute the metrics. We would like Amazon Q Developer to tell us how to write that SQL join statement.
Step 2. Conduct an exploratory analysis and generate candidates
Next, prompt Amazon Q Developer for candidate foreign keys to join the tables, and for SQL code to execute those joins. Generate an entity-relationship diagram (ERD) as a visual aid. Prompts do not have to be complicated. For example:
@workspace What columns of database tables sample.orderinfo and sample.skuinfo
would be best to join the two tables? Provide SQL code for the join. Draw an
entity relationship diagram that shows the joins between the two tables, and
includes only the fields involved in the join. Add a crow's foot cardinality
marker to indicate a 1:many relationship, and add it next to the high
cardinality table.
Each time tables are joined together, new aggregated metrics become available to drive business insights. Now, for instance, we can find the top selling SKUs in October thanks to our results:
Sometimes we need to look at code written in languages other than SQL to complete the data model. For example, the names of some vendors this company works with happen to appear in application PHP code as human readable strings, but are saved in the application database as numbers. The analytics data staged in Redshift only contain the numbers. So, we pull a copy of the PHP text file into @workspace, and ask Amazon Q Developer to translate the relevant string-integer mappings into a SQL case statement.
PHP Switch statement showing the mapping of Vendor Ids to String Names.
I am a Redshift database administrator and I am working on a data modeling
problem. I would like to write SQL statements to join tables sample.orderinfo
and sample.skuinfo. Please write that SQL to join the two tables. Also, I
would like to write a SQL case statement to recover all string values defined
in PHP that are represented as integer values in the database table.
The output of that prompt is shown below.
Amazon Q Developer automatically detected the PHP switch case statement, converted to SQL, and added it to the final query. Many other programming languages are supported, and modelers should try this technique with other kinds of source code. Note that data scientists and analysts may not know where to look in complex application code for these details, so this discovery-plus-code translation step is a net new benefit to our company that is only possible thanks to Amazon Q Developer.
Step 3. Create code to test the analysis
Now we request SQL source code for a battery of small test queries. These can return cardinality, grain, arithmetic, and null count results.
Please write a short SQL test to compute counts of the key fields that are used
in the joins, which will verify the cardinality assignments indicated in the
entity relationship diagram above. The SQL test should compare distinct counts
to total counts and null counts when it verifies the cardinality.
Step 4. Validate the results of the analysis
Run the test queries to see if the candidate solution from step 2 meets our goals. The “Insert at cursor” button at the bottom of the response is handy for this. The data modeler can easily spot an error in the join logic and ERD from inspecting the output of the test query. (Or, if it’s hard to interpret the results, keep making the test queries simpler.) If errors arise from the AI misinterpreting or miscalculating a result, or from a vaguely worded prompt, simply adjust the prompt in step 2 to fix the known errors, and repeat steps 2 – 4.
After a few iterations, taking from seconds to at most tens of minutes each, the modeling errors have been worked out and we arrive at a valid production query.
Key Benefits and Results
With this Amazon Q Developer powered solution and iterative approach, SmugMug has achieved highly accurate data modeling results across numerous database tables. Once the correct modeling configuration is established, various useful outputs may become available.
We already described production SQL, unit tests, and ERDs for documentation. By the end of the process, because Amazon Q Developer has a good understanding of the data it just modeled in its chat history, it will also generate useful Python machine learning programs to predict business trends. Here is a prompt for that, and a partial screenshot of the Python output:
Please write Python code to implement a linear regression that predicts the
quantity_ordered value based on other fields in the data set. Choose predictor
variables that are less likely to cause multi-collinearity problems.
This only shows the model training step, but the full response included all library imports, a Redshift query, feature engineering steps, ML performance metrics, and code for plotting the metrics. And the AI can produce other types of predictive models. For example, you can try:
Please write Python code to implement an XGBoost model that predicts the
quantity_ordered value based on other fields in the data set.
Ultimately, the solution has improved team productivity for both existing and new team members, while maintaining legacy knowledge needed to onboard new team members more efficiently. Key benefits include:
Reducing SmugMug data analyst and scientist’s time spent on data modeling tasks from days to hours, allowing them to reallocate this time to other high-priority projects.
Automating the generation of BI documentation and predictive ML, also saving crucial time.
Providing net new value by translating application code constant definitions into SQL. Due to organizational boundaries, we would not have achieved this without an assist from the AI.
Future Plans and Expansion
SmugMug conducted the initial data modeling use case testing with over a dozen data science team members and analysts. We are moving on to analyze more complex tables and data schemas, and generating Python code in Amazon SageMaker for ML tasks like data preparation, training, inference, and MLOps. From our experience, Amazon Q Developer has become a preferred internal tool for development that has a data modeling component, and its use continues to expand to different groups around the company.
For SmugMug’s data modeling projects, we continue to enhance the four-step process described above. In order to gather the most relevant context to solve a problem, we build vector database collections to pull from schemas, older SQL code, application source code, BI tool content, and curated documentation. The vector search operation surfaces the right content, and spares data modelers from manually searching in different code archives. We use ChromaDB to do the searches, and bring the results from ChromaDB into the workspace as additional files.
Conclusion
Using Amazon Q Developer for data modeling use cases, SmugMug has managed to increase data science and engineering team productivity by up to 100% when compared to prior workflows. To explore how Amazon Q Developer can benefit your organization, get started here. If you have questions or suggestions, please leave a comment below.
Today we are announcing the integration of AWS CloudFormation Hooks with AWS Cloud Control API (CCAPI). This integration enables the use of hooks to validate the configuration of resources being provisioned through CCAPI. In this blog post, we will explore the integration between CloudFormation Hooks and CCAPI by configuring an existing hook to work with CCAPI and then test that hook using the AWS CLI and Terraform.
Understanding CloudFormation Hooks
CloudFormation Hooks integrate seamlessly with your CloudFormation and CCAPI requests to perform validation of your resource configuration during resource create and update operations. You can create hooks using AWS Lambda, AWS CloudFormation Guard rules, or using code and the CloudFormation Command Line Interface (CFN-CLI). A hook can be triggered on change sets, entire stack templates, or by each resource and it will return back any discovered misconfiguration information. Hooks can be configured to warn or fail on the operation allowing you to prevent any misconfigured resources from being deployed in your account. Some key benefits of using CloudFormation Hooks with CCAPI include:
Enforcing security best practices
Applying organizational policies to resource deployments
Optimizing resource configurations for cost and performance
For this post we are going to use the new AWS CloudFormation Guard (Guard) hook AWS::Hooks::GuardHook. Guard is an open-source policy-as-code tool that allows you to validate your infrastructure configurations against company policy guidelines. It provides a domain-specific language (DSL) for writing rules to check both required and prohibited resource configurations. The new AWS::Hooks::GuardHook allows you to use the Guard DSL inside of a hook so you can easily implement your organizations guidelines. The result is you can use the same Guard rules in our local development environment, continuous integration and continuous deployment pipelines, and at deployment time (using hooks). To learn more about AWS::Hooks::GuardHook you can look at the blog.
This is what the configuration of the current Guard hook looks like.
This hook has been configured to log the Guard validation report to an Amazon Simple Storage Service (S3) bucket. Additionally, this hook is configured to use a rule from the AWS CloudFormation Guard registry. This rule will validate that an S3 bucket is using versioning. This hook is configured with an alias named My::Hooks::Guard.
Here is the rule for reference. This rule will validate that the property VersioningConfiguration is provided and that its value is Enabled.
let s3_buckets_versioning_enabled = Resources.*[ Type == 'AWS::S3::Bucket' ]
rule S3_BUCKET_VERSIONING_ENABLED when %s3_buckets_versioning_enabled !empty {
  %s3_buckets_versioning_enabled.Properties.VersioningConfiguration exists
  %s3_buckets_versioning_enabled.Properties.VersioningConfiguration.Status == 'Enabled'
  <<
    Guard Rule Set: ABS-CCIGv2-Standard
    Controls: section4b-design-and-secure-the-cloud-14-standard-workloads,section4b-design-and-secure-the-cloud-15-standard-workloads
    Violation: S3 Bucket Versioning must be enabled.
    Fix: Set the S3 Bucket property VersioningConfiguration.Status to 'Enabled' .
  >>
}
Configuring the hook to work with CCAPI
This announcement adds a new hook target that can easily be configured on your existing or new hooks. To configure the hook to work with CCAPI you will edit the configuration to include a new TargetOperations value of CLOUD_CONTROL. This hook is only enabled to execute on CREATE and UPDATE operations. Additionally HookInvocationStatus is ENABLED which will execute the hook and FailureMode will tell the hook to FAIL the operation if the resource is not compliant.
By using TargetOperations of ["RESOURCE", "CLOUD_CONTROL"] the Guard rules will work the same across CloudFormation resource operations and CCAPI operations.
Testing the hook using AWS CLI
Test your hook using the AWS CLI which allows us to create, update, delete, and list resources.
Start by creating a S3 bucket using CCAPI. In this example you are providing no properties for creating the S3 bucket. Run the command aws cloudcontrol create-resource --type-name AWS::S3::Bucket --desired-state {} Response:
Get the request status by using the RequestToken from the response above. Run the command aws cloudcontrol get-resource-request-status --request-token 2c7b6f5e-4083-4ef8-9a23-5c81472540b1
Response:
{
    "ProgressEvent": {
        "TypeName": "AWS::S3::Bucket",
        "RequestToken": "2c7b6f5e-4083-4ef8-9a23-5c81472540b1",
        "HooksRequestToken": "4a193a00-4c76-41fe-87b8-75b838f00bbe",
        "Operation": "CREATE",
        "OperationStatus": "FAILED",
        "EventTime": "2024-11-05T09:41:40.785000-08:00",
        "StatusMessage": "Request [4a193a00-4c76-41fe-87b8-75b838f00bbe] failed \ndue to the following failed invocations: [My::Hooks::Guard]"
    },
    "HooksProgressEvent": [
        {
            "HookTypeName": "My::Hooks::Guard",
            "HookTypeVersionId": "00000006",
            "HookTypeArn": "arn:aws:cloudformation:eu-central-1:123456789012:type/hook/My-Hooks-Guard/00000001/aws-hooks/AWS-Hooks-GuardHook/00000001.00000005",
            "InvocationPoint": "PRE_PROVISION",
            "HookStatus": "HOOK_COMPLETE_FAILED",
            "HookEventTime": "2024-11-05T09:41:38.978000-08:00",
            "HookStatusMessage": "Template failed validation, the following rule(s) failed: S3_BUCKET_VERSIONING_ENABLED. Full output was written to s3://<my-guard-hook-logging-bocket>/cfn-guard-validate-report/AWS--S3--Bucket-4a193a00-4c76-41fe-87b8-75b838f00bbe-RESOURCE-AWS--S3--Bucket-CREATE-PRE_PROVISION/1730828427591.json",
            "FailureMode": "FAIL"
        }
    ]
}
In the response you will see all hooks that were executed and their response in relation to the request. This response shows that the hook My::Hooks::Guard failed because of the rule S3_BUCKET_VERSIONING_ENABLED . You are also provided a s3 location for where the full Guard output is stored.
You can get the Guard results file by using the following command. Replace <path-from-previous-output> with the path provided in the previous output. Run the command aws s3 cp s3://<path-from-previous-output> -
We truncated the output as it can be very verbose.
Testing the hook using Terraform
The Terraform AWS Cloud Control Provider allows you to manage AWS resources using CCAPI and Terraform. By leveraging this provider you get the benefit of using hooks to validate the configuration of Terraform provisioned resources.
Create a new Terraform configuration file named main.tf with the following content:
Run the following commands to initialize Terraform and create an execution plan. Run the command terraform init followed by terraform plan.
Apply the configuration by running. Run the command terraform apply
Response:
...
awscc_s3_bucket.example: Creating...
╷
│ Error: AWS SDK Go Service Operation Incomplete
│
│   with awscc_s3_bucket.example,
│   on main.tf line 14, in resource "awscc_s3_bucket" "example":
│   14: resource "awscc_s3_bucket" "example" {
│
│ Waiting for Cloud Control API service CreateResource operation completion returned: waiter state transitioned to FAILED. StatusMessage: Request [d417b05b-9eff-46ef-b164-08c76aec1801] failed
│ due to the following failed invocations: [My::Hooks::Guard]. ErrorCode:
╵
In this response you can see that the hook My::Hooks::Guard failed and the request token is d417b05b-9eff-46ef-b164-08c76aec1801
You can get details on the hook invocation by running the command aws cloudformation list-hook-results --hook-target TargetType=CLOUD_CONTROL,TargetId=d417b05b-9eff-46ef-b164-08c76aec1801Response:
{
    "TargetType": "CLOUD_CONTROL",
    "TargetId": "d417b05b-9eff-46ef-b164-08c76aec1801",
    "HookResults": [
        {
            "InvocationPoint": "PRE_PROVISION",
            "FailureMode": "FAIL",
            "TypeName": "My::Hooks::Guard",
            "TypeVersionId": "00000006",
            "Status": "HOOK_COMPLETE_FAILED",
            "HookStatusReason": "Template failed validation, the following rule(s) failed: S3_BUCKET_VERSIONING_ENABLED. Full output was written to s3://my-company-guard-hooks-eu-central-1/cfn-guard-validate-report/AWS--S3--Bucket-d417b05b-9eff-46ef-b164-08c76aec1801-RESOURCE-AWS--S3--Bucket-CREATE-PRE_PROVISION/1730829108790.json"
        }
    ]
}
As with the AWS CLI you now know what rule failed and additional you have the S3 bucket location for the Guard log file.
You can get the Guard results file by running the command aws s3 cp s3://<path-from-previous-output> -. Replace <path-from-previous-output> with the path provided in the previous output.Response:
CloudFormation Hooks provide a powerful way to enforce best practices and compliance for your AWS resources. By leveraging CloudFormation Hooks and the Cloud Control API you can create consistent validation of your resources before deployment across many of your infrastructure as code solutions.
AWS CloudFormation is a service that allows you to define, manage, and provision your AWS cloud infrastructure using code. To enhance this process and ensure your infrastructure meets your organization’s standards, AWS offers CloudFormation Hooks. These Hooks are extension points that allow you to invoke custom logic at specific points during CloudFormation stack operations, enabling you to perform validations, make modifications, or trigger additional processes. Among these, the Lambda hook is a powerful option provided by AWS. This managed hook allows you to use Lambda functions to validate your CloudFormation templates before deployment. By using a Lambda hook, you can invoke custom logic to check infrastructure configurations on create or update or delete CloudFormation resources or stacks or change sets, as well as create or update operations for AWS Cloud Control API (CCAPI) resources. This enables you to enforce defined policies for your infrastructure-as-code (IaC), preventing the deployment of non-compliant resources or emitting warnings for potential issues. In this blog post, you will explore how to use a Lambda hook to validate your CloudFormation templates before deployment, ensuring your infrastructure is compliant and secure from the start.
Introducing Lambda Hook
The Lambda hook is an AWS-provided managed hook with the type AWS::Hooks::LambdaHook. It simplifies the integration of custom logic into CloudFormation stacks. This powerful feature allows you to focus on building and testing your custom logic as a Lambda function, without the complexity of creating a hook from scratch.
By using the Lambda hook, you can activate a pre-built hook and deploy your custom logic into a Lambda function using familiar tools like AWS CLI or AWS Serverless Application Model (SAM) or AWS Cloud Development Kit (CDK). This approach reduces the number of components you need to manage in your workflow, allowing for more streamlined operations. The Lambda hook also offers flexible evaluation capabilities, enabling you to respond to specific template properties or configurations as needed.
One of the key advantages of the Lambda hook is the enhanced control it provides. You can benefit from features such as VPC integration, local logging, and granular resource management, all while leveraging the power of AWS Lambda functions. To get started with the Lambda hook, you’ll need to activate it in your AWS account. This activation process eliminates the need for authoring, testing, packaging, and deploying a custom hook using the AWS CloudFormation Command Line Interface (CFN-CLI), significantly simplifying your workflow.
Example Use Case: S3 Bucket Versioning Validation
This blog post demonstrates using the Lambda hook to validate S3 Bucket versioning before deployment. While focused on S3 buckets, this approach can be applied to other resource types, properties, stack, and change set operations.
By leveraging the Lambda hook, you’ll streamline custom logic integration into your CloudFormation stacks. The process involves:
This example showcases how to enhance your infrastructure-as-code practices, ensuring compliant and secure deployments from the start.
Architecture
This section shows you how the Lambda hook and Lambda function work together to enhance your CloudFormation deployments.
Lambda hook and Lambda function
First, you need to create a Lambda function with the business logic to respond to the hook. Then, you need to create an IAM execution role with the necessary permissions to invoke the Lambda Function. Once you have the Lambda function and the IAM execution role, you can activate the AWS provided Lambda hook. Follow the steps in the documentation to activate a Lambda hook from the AWS console. Alternatively, you can activate it using the AWS Command Line Interface (AWS CLI) by using the activate-type and set-type-configuration commands. Lastly, you can also use AWS::CloudFormation::LambdaHook as a CloudFormation resource to activate and configure Lambda hook from a CloudFormation template. You can share this resource across your other accounts and regions using AWS CloudFormation StackSets by following this blog.
Lambda hook in action
The following diagram and explanation illustrate the step-by-step workflow of how Lambda hook integrates with your CloudFormation operations, providing a visual representation of the process from template creation to resource deployment or modification.
Diagram 1: Lambda hooks in action
The architecture diagram illustrates the step-by-step flow of how the Lambda hook is used during a CloudFormation stack operation.
Author a template: Author a CloudFormation template, including the necessary resources to configure.
Create the stack: The CloudFormation stack creation process has started, but the process of creating the defined resources in the template has not yet begun.
Request is received by CloudFormation service: When a resource creation, update, or deletion is requested, the CloudFormation service receives the request.
Invoke the Hook: The CloudFormation service then invokes the Lambda hook.
The hook invokes your the Lambda Function: The Lambda hook, in turn, triggers the execution of the Lambda function that was defined in the hook activation.
The Lambda function processes the request and responds back to the Hook: The Lambda function processes the request, performing validation, or additional tasks as required. The Lambda function then responds back to the Lambda hook.
The stack workflow progresses further in either continuing the resource creation/update/deletion with/without a warning or fails: Based on the Lambda function’s output, the Lambda hook either allows the stack operation to proceed with the resource operation (for example, creation of the resource), or deny the resource operation causing a rollback of the stack.
This workflow demonstrates how Lambda hook seamlessly integrates into the CloudFormation stack deployment process, allowing you to implement custom validations, enforce policies, and extend the capabilities of your infrastructure-as-code deployments through the power of Lambda functions. By leveraging the Lambda hook and the custom Lambda function, customers can extend the capabilities of their CloudFormation deployments, enabling advanced use cases such as resource validation, or additional task execution.
Sample Deployment
This section shows you how to enable the Lambda hook, which is of type AWS::Hooks::LambdaHook, and add the business logic in the Lambda function to validate the versioning configuration of an S3 bucket. The sample solution shown in this blog post demonstrates the hook triggering for the resource type AWS::S3::Bucket, and if you want to trigger this for every resource type, then you can use the Resource filter within Hook filters configuration that can take wildcard"AWS::*::*" as a value or multiple targets of resource types for example "AWS::S3::Bucket", "AWS::DynamoDB::Table", and you’ll also want to make sure that the Lambda Function has the logic to handle the additional resource type. You can also add additional Hook targets , for example to validate your STACK or CHANGE_SET.
In the example used in this blog post, you will configure the hook and activate on create and update operations operations. For more information about TargetFilters, see Hook configuration schema and for more information about Lambda hook see here. With these modifications, you need to consider two important points: First, you will need to handle the business logic to deal with different resource types in your Lambda function code. Second, additional pricing may apply based on your resource usage, for more details see the Lambda pricing page.
Creating the Lambda Function
You can create a Lambda function in several ways – on the AWS Console, using CloudFormation, using AWS CLI, or by directly invoking the API via SDK. In this section, we will cover creating a Lambda function with a few clicks on the AWS console. See Using Lambda with infrastructure as code (IaC) for deploying Lambda Function using SAM CLI, CDK or CloudFormation.
The Lambda Function code is designed to process the event received from the Lambda hook and validate the versioning configuration of the target S3 bucket resource. Here’s a detailed explanation of the code:
The function first extracts the relevant information from the event, including the invocation point and the target resource type.
It then checks if the current invocation point is in the configured HOOK_INVOCATION_POINTS list and if the target resource type is AWS::S3::Bucket. If not, the function returns a success response, skipping the validation for this particular invocation.
Note: this code that skips the validation is put here as a fallback logic in the event the user has not chosen to use TargetFilters. As this is a wildcard hook, without TargetFilters the hook will always be invoked for any AWS resource type described in the template, and since the hook targets preCreate, preUpdate, and preDelete by default, the hook will be invoked for these invocation points by default. To narrow the scope and reduce costs by avoiding to invoke the hook for all AWS resource type targets and invocation points, use TargetFilters.
Next, the function retrieves the resource properties from the event, specifically looking for the VersioningConfiguration property and its Status.
If the VersioningConfiguration property is not present or its Status is not set to Enabled, the function returns a failure response, indicating that the versioning is not enabled for the S3 bucket.
If the versioning is enabled, the function returns a success response.
The function also includes a fallback mechanism to return a failure response in case of any other exceptions. By evaluating this sample code, you can validate the versioning configuration of the S3 bucket during the CloudFormation stack creation and update processes, with your infrastructure-as-code policies.
Enabling Lambda Hook in your AWS Account/Region
Navigate to the AWS CloudFormation service on the AWS Console, then choose “Create Hook” → “with Lambda” from the main Hooks page:
Diagram 2: Create a Hook with Lambda console page
You will see the page explaining how the Lambda function work as a hook.
Diagram 3: Provide a Lambda function to Hook Console page
Provide the Hooks details: the name, the Lambda function it should take, the type, and the mode. You can also create your execution role directly from the console by choosing “New execution role”.
Diagram 3: Provide a Lambda function to Hook Console page
You can review the Lambda hook and activate it from the next page.
Diagram 4: Review Lambda hook Console page
Test a sample
In this section, you will test the hook and the Lambda Function that you activated for a S3 bucket resource.
Create an S3 Bucket without versioning
AWSTemplateFormatVersion: "2010-09-09"

Description: This CloudFormation template provisions an S3 Bucket without versioning enabled

Resources:
  S3Bucket:
    DeletionPolicy: Delete
    Type: AWS::S3::Bucket
    Properties:
      BucketName: !Sub test-bucket-versioning-1-${AWS::Region}-${AWS::AccountId}
You will see the hook invoking Lambda function and the Lambda Function responding back with a failure message since the Versioning is not enabled.
When you create or update a stack with the template above, the Lambda hook will be invoked, and the Lambda Function will respond with a failure message since bucket versioning is not enabled. The Lambda Function code will extract the resourceProperties from the event, check the VersioningConfiguration property, and find that the Status is not set to Enabled. As a result, if you use the example template above where you describe the S3 bucket without versioning enabled, the Lambda Function will send a failure response back to the hook, causing the CloudFormation stack operation to fail as shown in the following screenshot.
Diagram 5: Lambda Hook failure Stack
Create an S3 Bucket with versioning enabled You can try creating an S3 Bucket with versioning enabled to see how Hooks assessment succeeded.
AWSTemplateFormatVersion: "2010-09-09"

Description: This CloudFormation template provisions an S3 Bucket with Versioning enabled

Resources:
  S3Bucket:
    DeletionPolicy: Delete
    Type: AWS::S3::Bucket
    Properties:
      BucketName: !Sub test-bucket-versioning-2-${AWS::Region}-${AWS::AccountId}
      VersioningConfiguration:
        Status: Enabled
In this case, you will see the hook invoking the Lambda function and getting a success message since the Versioning is enabled
When you create a stack with this CloudFormation template, the Lambda hook will be invoked, and the Lambda Function will respond with a success message since the versioning is enabled. The Lambda Function code will extract the resourceProperties from the event, check the VersioningConfiguration property, and find that the Status is set to Enabled. As a result, the Lambda Function will send a success response back to the hook, allowing the CloudFormation stack operation to proceed as shown in the following screenshot.
Diagram 6: Lambda Hook success Stack
By testing these two scenarios, you can verify that the Lambda hook and the associated Lambda Function are working as expected, enforcing the S3 bucket versioning policy during CloudFormation stack operations.
In this blog post, you explored the capabilities of CloudFormation Hooks and how they can be leveraged to extend the functionality of your infrastructure-as-code deployments. Specifically, you learned about the Lambda hook, a pre-built hook that simplifies the process of integrating custom logic into your CloudFormation stacks.
By activating the Lambda hook, and deploying a custom Lambda Function, you were able to validate the versioning configuration of an S3 bucket during the CloudFormation stack creation and update processes. This approach allows you to enforce infrastructure-as-code policies and ensure compliance at the point of deployment, rather than relying on post-deployment checks or indirect governance mechanisms. The ability to leverage familiar tools and workflows, such as the AWS CLI, AWS SAM, CI/CD pipelines, or the AWS CDK, makes it easier to incorporate custom logic into your CloudFormation deployments. This reduces the overhead and complexity associated with traditional hook orchestration and packaging, empowering you to streamline your infrastructure-as-code practices.
As you continue to build and deploy your cloud infrastructure, consider exploring the various CloudFormation Hooks available, for example, see aws-cloudformation/aws-cloudformation-samples and aws-cloudformation/community-registry-extensions GitHub repositories. The approach demonstrated in this blog post can be applied to other resource types supported by CloudFormation, allowing you to validate and enforce policies for a wide range of infrastructure components, from EC2 instances and VPCs to databases and application services.
About the Author
Kirankumar Chandrashekar is a Sr. Solutions Architect for Strategic Accounts at AWS. He focuses on leading customers in architecting DevOps, modernization using serverless, containers and container orchestration technologies like Docker, ECS, EKS to name a few. Kirankumar is passionate about DevOps, Infrastructure as Code, modernization and solving complex customer issues. He enjoys music, as well as cooking and traveling.
Stella Hie is a Sr. Product Manager Technical for AWS Infrastructure as Code. She focuses on proactive control and governance space, working on delivering the best experience for customers to use AWS solutions safely. Outside of work, she enjoys hiking, playing piano, and watching live shows.
In today’s cloud-driven world, maintaining compliance and enforcing organizational policies across your infrastructure is more critical than ever. AWS CloudFormation, a service that enables you to model, provision, and manage AWS and third-party resources through Infrastructure as Code (IaC), has been a cornerstone for automating cloud deployments. While CloudFormation simplifies resource management, ensuring compliance with internal and external standards requires robust tools and strategies to align with organizational and regulatory requirements.
Enter the new managed hook for Guard, a new hook designed to seamlessly integrate compliance into your AWS CloudFormation workflows. AWS CloudFormation Hooks are a powerful tool that allow you to validate and enforce policies during the provisioning and management of resources in your CloudFormation stacks. With a Guard hook, you can now bring your AWS CloudFormation Guard rules directly into your CloudFormation stacks, change sets, and individual resources. This feature eliminates the need to incorporate the Guard runtime into custom hooks, simplifying compliance enforcement and enhancing your security posture.
What is a Guard hook?
A Guard hook is a service-managed CloudFormation Hook that integrates AWS CloudFormation Guard—a policy-as-code tool—directly into your CloudFormation deployment process. AWS CloudFormation Guard uses a domain-specific language (DSL) to define compliance rules in an easily readable and reusable format, enabling you to codify and enforce organizational policies. This hook allows you to automatically validate your CloudFormation templates against these established compliance rules, enforcing policies seamlessly without the need to manage custom Lambda functions or Guard runtimes. By identifying non-compliant resources early, it helps streamline deployments and ensures that your infrastructure aligns with organizational standards right from the start.
Benefits of Using a Guard hook
Guard hooks provide unique advantages by combining the flexibility of CloudFormation Hooks with the expressiveness of the Guard Domain Specific Language (DSL), giving you a powerful tool for infrastructure compliance and security. As a fully managed CloudFormation hook, Guard hooks eliminate the need for a custom hook implementation and management, allowing you to leverage AWS’s service-driven infrastructure to streamline policy enforcement.With a Guard hook, you can express compliance rules and configurations directly in the Guard DSL.
Guard hooks specifically add value by enabling these Guard-based compliance policies to be applied automatically during stack operations. This helps validate that your infrastructure consistently aligns with security and compliance standards, reducing the risks of misconfiguration and non-compliance. Additionally, Guard hooks allow you to take advantage of CloudFormation’s native stack-level and resource-level hooks, adding depth to your compliance by enforcing policies across entire stacks and individual resources alike.
Use Cases
Guard hooks can be applied in various scenarios to enhance compliance and security. In security compliance, for instance, it can ensure that all databases and storage services have encryption enabled or prevent security groups from allowing unrestricted inbound traffic. Regarding resource configuration, it can enforce the use of approved EC2 instance types or require specific tags on all resources for cost tracking and management.
For operational governance, Guard hooks can validate that resources do not exceed predefined thresholds, such as storage size, ensuring that resources are provisioned within acceptable limits. It can also enforce network policies by ensuring the use of approved VPCs and subnets, maintaining network security and compliance with organizational standards.
A resource hook in CloudFormation targets individual resources within a template, such as EC2 instances, S3 buckets, or IAM roles. It is particularly useful for enforcing specific standards or compliance requirements on individual resources, thereby helping customers ensure each one meets defined criteria. For instance, you could use a resource-level hook to enforce that every S3 bucket created through CloudFormation has server-side encryption enabled. In contrast, a stack or change set hook targets the entire CloudFormation stack as a single entity, allowing for the application of guardrails or validation requirements across all resources within the stack collectively. This helps to ensure that the entire stack, not just individual resources, aligns with set policies before the stack is created or updated. For example, a stack-level hook could be used to prevent a stack from containing certain types of resources or to ensure that a specific number of resources are created in each stack. Together, these hooks provide different layers of validation to enforce compliance and configuration standards at both the resource and stack levels.
Getting Started
Getting started with a Guard hook involves configuring the hook, uploading your Guard rules to Amazon S3, activating the hook, and enabling it to run against your CloudFormation stacks. Below are the detailed steps to help you set up and start using Guard Hook effectively.
Pre-requisites Create an Amazon S3 Bucket
If you do not have one already, you will need to create an S3 bucket in your region. This bucket will hold your Guard policy files and optionally the full Guard evaluation output if so desired.
Configuring a Guard hook Create your rule
In this section, you will provide an example of AWS CloudFormation Guard rules that help enforce best practices for Amazon S3 buckets. Please create a file called safebucket.guard and include the following rules:
# Rule Identifier:
#    S3_BUCKET_PUBLIC_WRITE_PROHIBITED
#
# Select all S3 resources from the incoming template (payload)
#
let s3_buckets_public_write_prohibited = Resources.*[ Type == 'AWS::S3::Bucket' ]

rule S3_BUCKET_PUBLIC_WRITE_PROHIBITED when %s3_buckets_public_write_prohibited !empty {
  %s3_buckets_public_write_prohibited.Properties.PublicAccessBlockConfiguration exists
  %s3_buckets_public_write_prohibited.Properties.PublicAccessBlockConfiguration.BlockPublicAcls == true
  %s3_buckets_public_write_prohibited.Properties.PublicAccessBlockConfiguration.BlockPublicPolicy == true
  %s3_buckets_public_write_prohibited.Properties.PublicAccessBlockConfiguration.IgnorePublicAcls == true
  %s3_buckets_public_write_prohibited.Properties.PublicAccessBlockConfiguration.RestrictPublicBuckets == true
  <<
    Violation: S3 Bucket public write access must be restricted.
    Fix: Set the S3 Bucket PublicAccessBlockConfiguration properties—BlockPublicAcls, BlockPublicPolicy, IgnorePublicAcls, RestrictPublicBuckets—to true.
  >>
}

# Rule Identifier:
#    S3_BUCKET_VERSIONING_ENABLED
#
# Select all S3 resources from the incoming template (payload)
#
let s3_buckets_versioning_enabled = Resources.*[ Type == 'AWS::S3::Bucket' ]

rule S3_BUCKET_VERSIONING_ENABLED when %s3_buckets_versioning_enabled !empty {
  %s3_buckets_versioning_enabled.Properties.VersioningConfiguration exists
  %s3_buckets_versioning_enabled.Properties.VersioningConfiguration.Status == 'Enabled'
  <<
    Violation: S3 Bucket versioning must be enabled.
    Fix: Set the S3 Bucket property VersioningConfiguration.Status to 'Enabled'.
  >>
}
In this file, you can define rules to prevent public write access and require versioning on all S3 buckets. Here’s what the two rules in this example do:
S3_BUCKET_PUBLIC_WRITE_PROHIBITED:
This rule identifies S3 buckets within a CloudFormation template and checks if the public write access is restricted. It ensures that each S3 bucket has PublicAccessBlockConfiguration properties enabled to block public ACLs, block public policies, ignore public ACLs, and restrict public buckets. If a bucket does not meet these criteria, a violation message is triggered, instructing the user to set these properties to true.
S3_BUCKET_VERSIONING_ENABLED:
This rule targets S3 buckets and verifies that versioning is enabled. The rule checks if the VersioningConfiguration property exists and has its Status set to 'Enabled'. If this configuration is missing or set incorrectly, it alerts the user to enable versioning on the S3 bucket, providing an additional layer of data protection.
These rules help you maintain strict security and operational best practices by ensuring that S3 buckets are configured according to compliance requirements. Place these rules in safebucket.guard, and you’re ready to start applying them to your CloudFormation templates using Guard Hook to enforce policies without any manual intervention.
Upload your rules to S3
The Guard hook expects your policy files to be uploaded to an S3 bucket to then be pulled down during hook execution time. The hook expects your rules to be either a single .guard file, or multiple .guard files uploaded as a .zip or .tar.gz
Once you have uploaded your Guard rule or Guard rules bundle to S3, take note of the S3 URI of the uploaded object, as you will need this later to configure the Guard hook. Example: s3://your-bucket-name/safebucket.guard
You can also get the S3 URI by copy-pasting it from the console
Authoring the Hook
You can author and activate a Guard hook from the console, CLI, and using the AWS::CloudFormation::GuardHook CloudFormation resource.
Console
You can use the new console flow to define and activate your hook. Click on Create a Hook and choose With Guard.
You can type in your Guard rules S3 URI from the step before, or you can browse your S3 bucket using the console button.
You can configure the hook by performing the following steps:
In the Hook Name field, enter My::Company::GuardHook.
Under Hook Targets, select both Stacks and Resources. By selecting both Stacks and Resources under Hook Targets, you’re instructing CloudFormation to apply your hook validations at both levels. This ensures that individual resources and the overall stack comply with your defined policies, providing a comprehensive safeguard across deployments.
For Hook Mode, choose Fail.
In Execution Role, select New execution role and enter my-guard-hook-role for the name if you want CloudFormation to create the necessary role and permissions. Alternatively, an IAM role ARN you created manually (learn more here).
While we didn’t include a filter in this example, you can limit the executions of the hook to the intended resource types by using a filter. For more information about filters view our documentation page. You can skip to the next step if you do not have anything to filter.
Review the hook details and then click the Activate Hook button.
Note: You can create your own type-name-alias → MyCompany::Hooks::GuardHook is just an example
Using the CloudFormation resource
Using the AWS::CloudFormation::GuardHook resource in a CloudFormation template allows you to enforce compliance checks and validations on your AWS resources before creating, modifying, or deleting them within a stack. By specifying Guard rules using the Guard domain-specific language (DSL), you can define policies to assess resource configurations and security standards. When integrated into a CloudFormation template, AWS::CloudFormation::GuardHook evaluates the resources during stack operations and can either block non-compliant actions or provide warnings, depending on the configuration. This tool benefits organizations by automating governance, enhancing security, and reducing manual intervention, which help ensure that deployments adhere to best practices and compliance requirements consistently across environments.
Here is an example of how to create a Guard hook with the AWS::CloudFormation::GuardHook resource in a YAML file.
For more about AWS::CloudFormation::GuardHook , see our docs.
Testing your hook (non-compliant stack)
Now at this point, the Guard Hook should be running against all S3 buckets deployed via CloudFormation stacks in your account. We can confirm this by creating a new stack, from the CLI.
To do so, create a file named s3-fail.yaml and add the following content:
AWSTemplateFormatVersion: "2010-09-09"
Description: This template creates a simple s3 bucket

Resources:
  DemoBucket:
   Type: AWS::S3::Bucket
Create a stack, and specify your template in the AWS Command Line Interface (AWS CLI). In the following example, specify the stack name as my-fail-stack and the template name as s3-fail.yaml.
You can see the completed assessment and the result (how many rules compliant vs. not compliant as part of describe-stack-events. As the Hook Failure Mode is set to Fail, you can see the stack status: CREATE_FAILED due to Hook failure.
For more information about downloading S3 Object, see our docs.
Testing your hook (compliant stack)
To do so, create a file named s3-pass.yaml and add the following content:
AWSTemplateFormatVersion: "2010-09-09"
Description: This template creates a simple S3 bucket with versioning enabled and public write access disabled

Resources:
  DemoBucket:
   Type: AWS::S3::Bucket
   Properties:
      VersioningConfiguration:
        Status: Enabled
      PublicAccessBlockConfiguration:
        BlockPublicAcls: true
        IgnorePublicAcls: true
        BlockPublicPolicy: true
        RestrictPublicBuckets: true
Notice in the template, our bucket now does not allow public write access and enables versioning.
Create a stack, and specify your template in the AWS Command Line Interface (AWS CLI). In the following example, specify the stack name as my-pass-stack and the template name as s3-pass.yaml.
Guard hooks revolutionize the way you enforce compliance and security policies within your AWS infrastructure. By leveraging a service-managed hook, you can seamlessly integrate policy validation into your CloudFormation deployments without additional operational overhead.
Take advantage of Guard hooks today to:
Simplify compliance enforcement.
Enhance your security posture.
Streamline your deployment workflows.
Focus on innovation rather than infrastructure management.
Ready to enhance your cloud compliance and security? Start integrating Guard hooks into your CloudFormation templates and experience a new level of simplicity and efficiency in policy enforcement.
Today, Amazon Web Services (AWS) announced the launch and general availability of Amazon Q Developer plugins for Datadog and Wiz in the AWS Management Console. When chatting with Amazon Q in the console, customers can access a subset of information from Datadog and Wiz services using natural language. Ask questions like @datadog do I have any active alerts? or @wiz what are my top 3 security issues today? to swiftly identify and fix problems without leaving the console.
Engineers and IT professionals can struggle with tool sprawl throughout an application’s operational lifecycle. Amazon Q Developer’s third-party plugin system works towards creating a single pane of glass for all your SaaS solutions.
In this post, we’ll explore:
How Q Developer plugins work
How to use these plugins to:
Understand the state of your infrastructure
Query and brainstorm on present issues
Generate code and CLI commands to use third-party systems
How to get started
Our goal is for you to gain a comprehensive understanding of how the third-party plugins will improve your operational productivity.
How do Q Developer plugins work
Amazon Q in the console uses the prefix you provide to select which plugin to query. This provides additional context on your request and the state of your infrastructure. Key processes include:
Intent recognition: Amazon Q Developer interprets your chat request’s intent. It searches through relevant APIs it can invoke and selects the correct workflow to get more context.
API invocation: Amazon Q Developer then calls the appropriate third-party APIs to gather relevant information. Neither the AWS context included in the chat nor any information from your prompt is passed to the third-party.
Response Generation: After obtaining the enriched context and original prompt, Amazon Q Developer composes a complete prompt. Amazon Q uses this to generate the best response.
Guardrails: The system checks the response against Amazon Q Developer guardrails to ensure it follows best practices.
This system enables Amazon Q Developer to, understand intent, request additional information, and provide rich assistance across your infrastructure and application operations.
Let’s see how each of the third-party plugins can help in a set of real-world use-cases.
Amazon Q Developer plugin for Datadog
Datadog, an AWS Advanced Technology Partner and observability and security platform for cloud applications, provides AWS customers with unified, real-time observability and security across their entire technology stack. Datadog unifies all of your telemetry in one place, so teams can troubleshoot, optimize, and secure resources at scale. If you use Datadog to monitor your AWS infrastructure and applications, you can query a subset of information from Datadog without leaving the AWS console by prefixing your Amazon Q queries with @datadog.
Learn to use Datadog in your workloads
You can ask about how Datadog features work with certain AWS services, by asking questions like @datadog how do I use APM on my EC2 instance?
Retrieve and summarize cases and monitors
You can ask about specific cases, monitors, or specify properties of a case to get more information about it and include it in your conversation by asking questions like @datadog list my cases. With a follow up to quickly get a summary of your top cases, @datadog summarize my top cases
Check and list monitors in alarm
You can ask about specific application monitors as well, including which monitors are in alarm, Amazon Q Developer also allows follow-up questions about which alarmed monitors. You can start with a question like, @datadog list my current monitors
And then follow it up with a question like, @datadog List some of the resources that are triggering the alarm
Amazon Q Developer plugin for Wiz
With Wiz, organizations can democratize security across the development lifecycle, empowering them to build fast and securely. As an AWS Security Competency Partner, Wiz is committed to effectively reducing risk for AWS customers by seamlessly integrating into AWS services. If you use Wiz to monitor your AWS infrastructure and applications, then you can query Wiz without leaving the console by prefixing your queries with @wiz.
View issues with critical severity
You can ask Q Developer to retrieve the specifics of your issues in Wiz, the plugin can currently return up to 10 issues and you can focus on a specific severity with a question like, @wiz list the issues with critical severity With that response, we can also ask it to find the top issues, with a follow-up question like, @wiz can you specify the top 5?
Find your critical resources
Wiz defines the security posture of your AWS resources based on their configuration and how many critical issues that are associated with them. Amazon Q Developer can ask Wiz which are the least secure resources with a question like, @wiz what are the critical resources in my AWS environment?
List issues based on certain properties
Wiz tracks security issues that exist in your AWS account and you can ask Amazon Q Developer to list issues based on date, status, severity or type, with questions like, @wiz what issues are due next?
Assess issues with security vulnerabilities
Wiz tracks external vulnerabilities and exposures that can potentially pose a security threat associated with your current resources and issues. Amazon Q Developer can ask Wiz which are the pertinent vulnerabilities with a question like, @wiz what are my issues that have been created in the last 7 days?
Getting Started
To enable third-party Plugin capability in the Amazon Q Developer console:
To use third-party plugins, subscribe to Amazon Q Developer Pro Tier if you don’t already have it. This activates plugins at an organizational level.
If you don’t already have a Amazon Q Administrator Role/User, create one using either the AmazonQFullAccess / AmazonQDeveloperAccess managed policies, or follow the instructions in the Q Developer user guide for security and IAM permissions.
Configure the plugins – To activate the plugins, you must configure their credentials to authenticate into the third-party system. This is possible through a new tab called “Plugins” in the Amazon Q Developer dashboard. The plugins require credentials from the third parties to authenticate and call APIs specific to your accounts. They’re stored in your AWS account in Secrets Manager.
Datadog – Follow the instructions in the Datadog API documentation to create a Datadog API key and copy over the Site URL, API Key, and application key to authorize Q Developer with your instance of Datadog.
Wiz – Follow the instructions in the Wiz Service account documentation to create a client ID, the client secret generated by wiz, and then retrieve the Wiz API endpoint URL to connect Amazon Q Developer to Wiz.
Query the new plugins – With the @datadog and @wiz prefixes, you can ask a wide variety of questions and get operational assistance leveraging from third-party SaaS products. This allows you to integrate data from all sources with lower overhead and friction.
Iterate and refine – Try rephrasing or explicitly including more context about the request by mentioning dates or issue severity. Providing more relevant information helps Amazon Q Developer better understand your request.
For best results with third-party plugins, understand what you’re looking for and use terminology specfic to the third-party. Avoid overly broad queries to guide Amazon Q Developer effectively.
Conclusion
In this post, we introduced Amazon Q Developer’s third-party plugins in chat via the @datadog and @wiz prefixes highlighting the benefits of using plugins when trying to leverage generative AI across multiple services. By allowing Q Developer to understand and analyze the state of your infrastructure across services, third-party plugins unlock new boundaries for operational productivity gains.
AWS CloudFormation makes it easy to model and provision your cloud application infrastructure as code. CloudFormation templates can be written directly in JSON or YAML, or they can be generated by tools like the AWS Cloud Development Kit (CDK). These templates are submitted to the CloudFormation service and the resources are deployed together as stacks, in dependency order. Stack events can be viewed in a tabular format in the console, which provides fine-grained details about each event. And now there is a new feature that offers a more visually intuitive view of the events called the deployment timeline view, which provides a visualization of the sequence of actions CloudFormation took in a stack operation. This visual timeline shows you the exact order in which resources are provisioned, dependencies between resources, provisioning times, and likely root causes for any deployment failures. It complements the existing tabular stack events view by giving you additional context and visibility into what happens behind the scenes during deployments.
To use the new deployment timeline view, simply initiate a stack create, update, or delete operation. In the AWS CloudFormation Console, choose the Events tab, then click the Timeline view tab next to Table View. As CloudFormation begins provisioning the resources defined in your template, you’ll see each resource operation appear as a bar in the timeline view. The resources are organized in a vertical stack, chronologically ordered with the most recent resource operation at the top. Each resource action is visualized horizontally, segmented by different color bars for each resource action:
In dark mode, in-progress rollback and completed rollback switch colors.
You can hover over any bar to see additional details like the full resource name and the start/end times of the resource action. If a deployment fails, CloudFormation will highlight the resource operation that was the likely root cause node in a red-and-white striped bar, which you can hover over to see the specific failure reason.
Creating a simple stack
Create a simple stack using CloudFormation Console. You will initiate a deployment and then explore the visual timeline view.
1. From the CloudFormation console, click Create stack and then choose with new resources.
2. In the Create stack wizard, click Choose an existing template and then choose Upload a template file. Click Choose file to select and upload the template file of the stack to deploy. In this blog you will use the template available here. Download the template or you can use your own template. If you decide to use your own template, it will result in a different deployment timeline view.
3. Once the template is uploaded to S3, click Next, then provide a stack name and parameters if needed. Complete the remaining stack deployment configuration steps, then initiate the stack creation operation.
4. On the stack events page, click the Deployment timeline tab next to Events.
You should now see the deployment timeline view rendering in real-time as CloudFormation provisions the VPC networking resources first, followed by the security group, subnet, and lastly, the EC2 instance.
The above timeline shows, from the bottom to the top, bars representing each resource CloudFormation provisioned, with virtual vertical dependency lines showing the orders in which each resource operation occurred. The bars change colors as operations progress from blue (in-progress), to yellow consistency check, green (success) or red (failed).
Hover over any bar to see details like the start/end time of each deployment phase and the full resource name. The detailed information in the graph’s popover shows that CloudFormation created the InternetGateway resource in two seconds, then waited for 15-seconds to check if the resource was fully operational before marking as complete. This phase is called the resource consistency check phase, also known as the resource stabilization phase. It allows CloudFormation and other Infrastructure as Code (IaC) tools to ensure resilient deployments. To learn more, read this post about CloudFormation optimistic stabilization strategy.
Stack in a rollback complete state
When a stack deployment fails, CloudFormation rolls your stack back to its initial stable state before the current stack operation. The deployment timeline view below shows a failed stack operation in a complete rollback state. You can see the likely root cause resource highlighted in a red-and-white striped color so you can instantly identify it and start troubleshooting.
Figure 8: Deployment timeline view of a stack in rollback complete
Conclusion
The new CloudFormation deployment timeline view provides visibility into the orchestration flow and dependencies involved when CloudFormation provisions resources defined in your infrastructure-as-code templates. With this visual timeline view, you can quickly identify the root cause of deployment failures before operations complete and better understand the provisioning process. This feature is available now in all AWS regions where CloudFormation is supported. Visit the CloudFormation console to start using deployment timeline view.
Recently, we launched a new AWS Cloud Development Kit (CDK) L2 construct for Amazon CloudFront Origin Access Control (OAC). This construct simplifies the configuration and maintenance of securing Amazon Simple Storage Service (Amazon S3) CloudFront origins with CDK. Launched in 2022, OAC is the recommended way to secure your CloudFront distributions due to additional security features compared to the legacy Origin Access Identity (OAI). This new construct makes it easier for you to use the latest origin access best practices to build and manage your CloudFront distributions.
CDK is an open-source software development framework for defining cloud infrastructure in code and provisioning it through AWS CloudFormation. A primary part of CDK is the AWS CDK Construct Library which is a collection of pre-written constructs. Constructs are the basic building blocks of CDK applications. They help reduce the complexity required to define and integrate AWS services together.
There are different levels of constructs, starting with Level 1 (L1) which map directly to a single CloudFormation resource and offer no abstraction. L1 constructs are auto-generated, which means you can build any CloudFormation resource using CDK. The power of the CDK starts with Level 2 (L2) and higher constructs. L2 constructs, also known as curated constructs, are developed by the CDK team and provide a higher-level abstraction through an intuitive intent-based API. You can read more about constructs and their benefits in the CDK user guide.
In this post we’ll explore:
The reasoning behind the creation of a new L2 construct for OAC
How to use the new OAC construct
How to migrate from the legacy OAI construct to the new OAC construct
Background
Amazon CloudFront is a global content delivery network that reduces latency by delivering data to viewers anywhere in the world. CloudFront can connect to different types of locations or origins, such as S3, AWS Lambda function URLs, and custom origins. A full list of supported origins can be found in the CloudFront user guide.
At launch, the new L2 construct supports OAC with S3 origins. Using OAC with S3 allows you to keep your S3 bucket private, yet accessible, through CloudFront. This forces users to access content only through CloudFront where other security features can be applied, like AWS WAF.
There are two ways to restrict buckets to only CloudFront, using OAI (legacy) or OAC (recommended). Both OAI and OAC allow you to secure your buckets, but OAC offers additional benefits, including support for:
Enhanced security practices like short term credentials, frequent credential rotations, and resource-based policies
Prior to this release, customers had to piece together L1 constructs as well as use escape hatches in order to implement OAC.
The introduction of the new L2 construct simplifies the process by enhancing abstraction and reducing complexity. It makes it easy to use OAC while still offering the flexibility to customize all existing properties available by building with L1’s.
Let’s see the construct in action!
Using the L2
We modified the existing CloudFront Origins L2 to add OAC support. With this change, the S3Origin class has been deprecated in favor of S3BucketOrigin for standard S3 origins, and S3StaticWebsiteOrigin for static website S3 origins.
Using OAC with a standard S3 origin is as simple as passing your bucket as a parameter to the new S3BucketOrigin class using the withOriginAccessControl method.
In the example below, we define a private bucket and let the new L2 construct handle all the OAC configuration for us.
const s3bucket = new s3.Bucket(this, "myBucket", {
    bucketName: `${cdk.Stack.of(this).stackName.toLowerCase()}-oacbucket`,
    blockPublicAccess: s3.BlockPublicAccess.BLOCK_ALL,
    accessControl: s3.BucketAccessControl.PRIVATE,
    enforceSSL: true,
});

const distribution = new cloudfront.Distribution(this, "myDist", {
    defaultBehavior: {
        origin: origins.S3BucketOrigin.withOriginAccessControl(s3bucket),
    }
});
This code defines a S3 bucket configured to block all public access, enforces SSL, and uses private access control. It also defines a CloudFront distribution with the S3 bucket as its origin using the default OAC settings from the OAC construct. By default, the signing behavior is set to “always” and the signing protocol to “sigv4” as is shown below:
Figure 1 – Default OAC Settings for the S3 Origin
In typical CDK fashion, the L2 provides sane defaults out-of-the-box but allows you to customize. Some examples of customizing with the L2, include:
Granting permissions for dynamic requests (write/delete access)
Migrating to the new construct but continuing to use OAI
S3 Origin with Customer Managed KMS
It is a recommended security best practice to encrypt S3 objects at rest. As detailed in the S3 user guide, using SSE-KMS gives you additional flexibility to meet encryption-related compliance requirements.
If using SSE-KMS, CloudFront must have permission to at least decrypt objects using your AWS KMS key. With the new changes, simply configure your bucket to use an AWS KMS key and the construct will take care of the permissions updates.
The following example shows how to create an SSE-KMS encrypted S3 bucket and use it as a CloudFront origin with OAC:
Create an AWS KMS Key.
Create the S3 Bucket with the encryptionKey property set to the AWS KMS key and encryption as KMS.
Create the CloudFront distribution and use the new S3BucketOrigin class with OAC.
const kmsKey = new kms.Key(this, "myKey");

const myBucket = new s3.Bucket(this, 'myEncryptedBucket', {
  encryption: s3.BucketEncryption.KMS,
  encryptionKey: kmsKey,
  objectOwnership: s3.ObjectOwnership.BUCKET_OWNER_ENFORCED,
});

new cloudfront.Distribution(this, 'myDist', {
  defaultBehavior: {
    origin: origins.S3BucketOrigin.withOriginAccessControl(myBucket)
  },
});
Due to circular dependencies between the bucket, the KMS key, and the CloudFront distribution, when we synthesize the above code, a warning message similar to the following may appear:
To avoid a circular dependency between the KMS key, Bucket, and Distribution during the initial deployment, a wildcard is used in the Key policy condition to match all Distribution IDs.
After the initial deployment, it is recommended to further restrict the policy to adhere to security best practices. Here is an example of how to use an escape hatch to update the policy:
Note: update the existing KMS Key policy to include the statements in scopedDownKeyPolicy
const scopedDownKeyPolicy = {
    Version: "2012-10-17",
    Statement: [
        {
            Effect: "Allow",
            Principal: {
                AWS: `arn:aws:iam::${this.account}:root`,
            },
            Action: "kms:*",
            Resource: "*",
        },
        {
            Effect: "Allow",
            Principal: {
                Service: "cloudfront.amazonaws.com",
            },
            Action: ["kms:Decrypt", "kms:Encrypt", "kms:GenerateDataKey*"],
            Resource: "*",
            Condition: {
                StringEquals: {
                    "AWS:SourceArn": `arn:aws:cloudfront::${this.account}:distribution/<Distribution ID>`//replace <Distribution ID> with the ID of the deployed CloudFront Distribution
                },
            },
        },
    ],
};

const cfnKey = kmsKey.node.defaultChild as kms.CfnKey;
cfnKey.addOverride("Properties.KeyPolicy", scopedDownKeyPolicy);
Considerations when migrating to the new construct
If you have an existing OAI implementation using the now-deprecated S3Origin class, switching to OAC has potential for application downtime. CloudFront could temporarily lose access to the S3 bucket while the CloudFormation is deploying.
To avoid downtime, it is recommended to perform the upgrade across multiple deployments. This will explicitly give CloudFront permissions to both OAC and OAI in the S3 bucket policy before the migration is performed.
At a high level, the three steps are:
Deployment 1: update the bucket policy to explicitly allow CloudFront access
Deployment 2: switch to the new construct
Deployment 3: optionally remove the code that updated the bucket policy in step 1
For detailed instructions, see the Migrating from OAI to OAC section of the CDK API docs.
Conclusion
In this post, we introduced the new AWS CDK L2 construct for Amazon CloudFront Origin Access Control (OAC), highlighting the advantages of using OAC instead of OAI to secure your Amazon S3 CloudFront origins. We showcased practical implementations of the new construct, focusing on using defaults of the L2 construct along with how to customize for your use case.
To summarize, the new L2 construct and OAC offers these benefits:
Simplified configuration: the L2 construct simplifies the process of configuring OAC in your CDK application to set up secure access controls between CloudFront and S3 buckets
Using SSE-KMS encryption: the L2 construct will automatically add the IAM policy statement to the AWS KMS key to allow access to OAC
Ability to customize: the L2 construct offers properties to override defaults, like changing the signing behavior
Easily migrate from OAI to OAC: the L2 construct offers options to migrate from OAI to OAC based on your application’s downtime tolerance
At launch, the construct supports an Amazon S3 origin. If there is a particular origin that you are looking to see added to the construct library for OAC, please submit a feature request issue in the aws-cdk GitHub repo. For example, if you are interested in Lambda support for OAC, add your feedback to this feature request.
If you’re new to CDK and want to get started, we highly recommend checking out the CDK documentation and the CDK workshop.
Any organization that manages software libraries and applications needs a standardized way to catalog, reference, import, fix bugs and update the versions of those libraries and applications. Semantic Versioning enables developers, testers, and project managers to have a more standardized process for committing code and managing different versions. It’s benefits also extend beyond development teams to end users by using change logs and transparent feature documentation. This alleviates the operational burden of communicating changes for each release cycle.
In this post, we dive deep into how Semantic Versioning works and how to use the NodeJS package semantic-release/npm in a GitHub Actions continuous integration and continuous delivery (CI/CD) pipeline to automatically version an Amazon Web Services (AWS) Cloud Development Kit (AWS CDK) project. Once we’re done, you’ll be ready to deliver AWS CDK projects that are automatically versioned so your team can focus more on code instead of versioning for each release.
How does Semantic Versioning work?
With Semantic Versioning, version number changes convey a specific meaning about the underlying code change. This helps others to understand what has changed from one version to the next.
Semantic Versioning is defined in a Major.Minor.Patch format, which is a guideline to track the scope and potential impact of changes for feature development, major updates and bug fixes. The Major version number change signifies that this release will have breaking changes and any upgrade to this version should be validated for backward compatibility. The Minor version number change signifies a feature release in a backward-compatible manner. Finally, the Patch version number signifies a small insignificant change or a bug fix and users can upgrade to this version without introducing breaking changes or new features.
Each version number is always incremented by one digit and when a higher digit increments, the lower digits reset to zero. For example, version 1.5.2 means that the software is in its first major version, and has released 5 features with 2 patches implemented. When a new feature is added, it will be released as version 1.6.0. If there are any bugs reported and a fix is release for that bug, the next release version will be 1.6.1. For a version 2.0.0 release there will be breaking changes, and may not be backward compatible with previous 1.x.x versions.
What is semantic-release?
Now that we have covered how Semantic Versioning works, and why it’s useful in software projects, let’s review semantic-release. It is a Node.js tool that simplifies Semantic Versioning management. Semantic-release can do more than just apply Semantic Versioning to your projects. With a variety of plugins available, you can track what sort of changes are being made with commit analysis or by generating a changelog for each release. This automates what would otherwise have been a manual and time-consuming process to create and review roadmaps and documentation tracking the new features and fixes that comprise a release. Semantic-release is also straightforward to integrate with CI tools such as GitHub Actions, GitLab CI, Travis CI, and CircleCI 2.0 workflows.
Unfortunately, if your commit messages don’t match the format semantic-release requires, the automatic versioning won’t work correctly. To verify that commit messages are in the right format, you can integrate tools such as commitizen or commitlint, which can validate that commit messages are in a valid format.
Using semantic-release
Commit message formats
By default, semantic-release uses Angular Commit Message Conventions, however the commit message format can be altered by using config options. Let’s take a quick look at the three different types of commit messages, fixes, features, and breaking changes.
Patches and fixes
For patch or fix commits, you need to start your commit message with “fix(context):”. This tells semantic-release that this is a minor patch—meaning that if your version is 0.0.1, after this commit is merged the version will be incremented to 0.0.2. Following is an example commit message.
fix(printer): inform user when printer is out of paper
Features
Feature commit messages start with “feat(context):” which indicates to semantic-release that this is a feature release, also referred to as a minor release. If your version is 0.1.0, after a feature commit is merged, the version will be incremented to 0.2.0. Following is an example of a feature commit.
feat(printer): add option for printing in color
Breaking changes
Breaking change commits are intended for marking a major breaking change—meaning that the commit introduces changes that are not compatible with existing or previous versions. The way that commit messages are marked as breaking changes is slightly different than the previous commit types. For a breaking change, the commit footer needs to include “BREAKING CHANGE:”. For example, a breaking change commit, might look like the following.
perf(printer): remove color printing option
BREAKING CHANGE: The color printing option has been removed. The default black and white printing option is always used for performance reasons.
Release change log
To generate a release change log, we only need to add the semantic-release/changelog plugin to the package.json file. We’ll demonstrate how to do this in the next section.
Adding Semantic Release to an AWS CDK project
To demonstrate semantic-release in action we will build an example with AWS CDK and the NPM semantic-release library. All code provided in the remainder of this blog can be found in the semantic-versioning demo repository (aws-cdk-semantic-release) on GitHub.
To get started we’ll need to create a Node.js CDK application, add semantic-release and its plugins, commit changes, then build the project. If you don’t have AWS CDK installed yet, check out the Getting Stated with CDK guide.
To begin, navigate to the folder where the project will be saved. Next, we initialize a new AWS CDK project and add semantic-release. Then, we configure the branches that Semantic Versioning should be applied to and add a few NPM plugins to extend the functionality of semantic-release. While there are many plugins available, only a few are needed to get started. Below, we’ll walk through which plugins to install and how to install them.
Initiate a new AWS CDK Typescript project and add semantic-release
In a command terminal, navigate to the folder where you want to store your AWS CDK project and run the following three commands. The first line will create the project and the next two will install the semantic-release NPM and Git plugins in the AWS CDK project.
We need to tell NPM which branches can trigger a new release. In the example we’ll use the main branch and the staging branches for release. We will add a new section to the package.json file along with the branches we want to use for releases.
"release": {
  "branches": ["main"]
}
Add supporting plugins to package.json
In order for semantic-release to pick up commits, generate release notes, and be able to perform a release with GitHub we need to add the commit-analyzer, release-notes-generator, changelog, NPM, Git, and GitHub plugins. Add the following plugins section to the package.json file after the “release” section we added in the previous step.
Now that we have everything configured, new merges and commits to the main branch will kick off a CI/CD pipeline through GitHub Actions that builds the project and increments the version. To verify that everything is working correctly, we’ll alter the CDK code to include an AWS Lambda function. Afterward, we’ll commit changes to the main branch to verify that semantic-release is working correctly.
Make a change, commit, push and verify
In the AWS CDK project lib/aws-cdk-semantic-release-stack.ts file we’ll update the visibilityTimeout duration to 600, then commit the changes. We want to be sure to use the Semantic Versioning format for the commit message so that our changes are versioned correctly. For this we use the following commit message.
“fix(sqs-visibility): increased visibility timeout to 600”
After committing the changes, we push the changes to the remote GitHub repository to initiate the GitHub Actions build process. Once the build is complete, we see that the build number has been incremented from the previous version. You can review the releases for the sample code to see how it has been versioned. Following are examples of what it should look like before and after executing this. Please note that the version numbers depicted may not match yours.
Screenshot of GitHub releases page showing release 1.0.0 and the associated features changelog
Figure 1 – Before the new commits
Screenshot of GitHub releases page showing a previous release and the latest release along with their respective versions of 1.1.0 and 1.1.1
Figure 2 – After GitHub Actions generates a new build
Conclusion
Semantic Versioning offers a structured and reliable way to manage software changes. When paired with the significant benefits of using Node.js packages like semantic-release, version management can become effortless. All of this enables automated version management Node.js projects such as AWS CDK pipelines for automated code deployment. It enhances clarity, stability, and collaboration, while also supporting automation and fostering user confidence.
By adopting Semantic Versioning, development teams can achieve more predictable and efficient workflows, ultimately leading to higher quality software. It also builds confidence among users without going into much details with respect to software upgrades and backward compatibility. As a best practice, start incorporating Semantic Versioning for existing and future applications.
Contact an AWS Representative to know how we can help accelerate your business.
Reference
CDK setup and deployment of application with CDK V2 Construct:
The release of Amazon Q Developer and its ability to be integrated into AWS Chatbot allows users who use Microsoft Teams or Slack to stay within their communication platform and interact with a conversational generative artificial intelligence (AI) AWS expert.
Amazon Q Developer is a conversational generative AI chatbot that provides AWS assistance in the form of best practices, documentation, and answers your AWS related questions. AWS Chatbot is a service that lets you interact with AWS services directly from your communications platform such as Microsoft Teams, Amazon Chime, or Slack. Users can ask Q about best practices, building solutions, troubleshooting issues, and more, creating a productive and collaborative environment. Users can also interface with Chatbot to run AWS CLI commands or open support cases all within Slack.
In this post, we show you how you can leverage Q Developer and Chatbot in your Slack workspace by highlighting a number of use cases along with solution screenshots that can enhance a company’s AWS productivity. We will also showcase an architecture diagram, detailing the flow of actions and the use of different services. To learn more about how to implement Q Developer and Chatbot in Slack, refer to this documentation.
Disclaimer: The information and solutions provided by Q Developer are based on patterns from AWS-related data and best practices. While we strive to offer accurate and helpful guidance, please note that the suggestions may not always be fully accurate or applicable to every situation. It is essential to conduct additional research and verify the information with official AWS documentation or consult with AWS support before implementing any recommendations. Always use your judgment and consider the specific requirements of your environment when making decisions based on AI-generated advice.
Leveraging Q Developer and Chatbot
Q Developer and Chatbot serve a wide range of personas across an organization, catering to both AWS-savvy users and those with limited cloud expertise. Software engineers, for instance, can leverage Q Developer to quickly locate documentation, troubleshoot issues, or find best practices, streamlining their workflow. Security engineers can interact with Chatbot to monitor incidents and receive real-time alerts. Even non-technical users, like project managers or operations staff, can benefit from these tools without needing deep cloud knowledge. Together, these tools enhance productivity and collaboration across the company, regardless of technical expertise.
Use Cases
The use cases section is split into two categories, one for Q Developer, and the other for Chatbot. Both services provide unique abilities to interact with AWS to get the response you are looking for and can be accessed by sending a message to @aws on Slack. Q Developer allows users to ask questions in natural language and responds back with a response and a list of sources. Chatbot allows users to open support cases and to run a number of AWS CLI commands for services such as S3, Lambda, and CloudWatch.
Q Developer Use Cases
Q Developer is a versatile tool designed to assist teams for a number of AWS related use cases. In this post, we will focus on training and onboarding, troubleshooting issues, and implementing AWS best practices.
Training and Onboarding
Benefit: Q Developer can act as a virtual learning assistant, providing personalized training and learning paths for users based on their role, skill level, and current projects. It helps team members stay updated with the latest AWS features and best practices, enhances their skills, and ensures that they can leverage AWS services effectively and efficiently. By offering targeted resources, Q Developer supports continuous learning and helps users prepare for AWS certifications or new roles.
Use Case:AWS Beginner Recommendations. When a new employee joins the team, Q Developer can help them get up to speed by suggesting beginner-level tutorials and essential AWS concepts based on the team’s current tech stack and projects.
Figure 1 – AWS Beginner Recommendations
Use Case: Certification Guidance. An employee aims to get another AWS certification. They can ask Q Developer to provide a structured learning path with recommended courses, study guides, whitepapers, and practice exams to prepare effectively.
Figure 2 – Certification Guidance
Troubleshooting Issues
Benefit: Q Developer provides targeted troubleshooting guidance, helping users to diagnose and resolve issues efficiently. By leveraging AWS service documentation, best practices, and community discussions, Q Developer reduces the time spent on searching for solutions and allows users to focus on resolving issues faster. This improves operational efficiency and minimizes downtime or disruptions.
Use Case:Optimization Recommendations. A developer is facing an issue with running their application on EC2 during peak hours and is looking for recommendations to diagnose the issue.
Figure 3 – Optimizations Recommendations
Use Case:Service Troubleshooting. An engineer is working on configuring API Gateway with their application but receives a 504 Gateway Timeout error. Q Developer can look up HTTP response codes for specific services and recommend a plan to tackle the issue.
Figure 4 – Service Troubleshooting
Best Practices
Benefit: Q Developer provides access to AWS best practices, ensuring that users can build, manage, and maintain their cloud infrastructure effectively. By adhering to best practices, users can optimize their applications for performance, security, scalability, and cost-efficiency. Q Developer helps users stay informed about evolving best practices for using AWS services, ensuring their deployments are up-to-date and compliant with industry standards.
Use Case:Designing Resilient Architectures. A solutions architect is designing a new application on AWS and wants to ensure it’s highly available and fault-tolerant. By asking Q Developer for best practices, they can receive guidance on a number topics including region selection, software, architecture, and deployment strategies to maximize uptime and reliability.
Figure 5 – Designing Resilient Architectures
Use Case: Deploying Applications for Operational Excellence. An engineer is looking for best practices to deploy an application onto AWS Elastic Beanstalk. Q Developer can assist with providing specific tips for the job that conforms with AWS’ operational excellence pillar found in the AWS Well-Architected Framework.
Figure 6 – Operational Excellence
Chatbot Use Cases
Chatbot can be used to run AWS CLI commands, open support cases, and more within Slack. To learn more about how to get started with these commands, please visit Chatbot’s documentation and refer to this AWS Blog for additional information.
Using Chatbot and Q Developer Together
We can use Chatbot and Q Developer together to provide clarity in situations where an organization receives alerts on their Slack channel. For example, you can configure Chatbot to receive notifications using Amazon Simple Notification Service based off of rules set up within Amazon EventBridge and it will be delivered directly into your Slack channel. Given that an organization can have many types of notifications enabled for their AWS services, there may be times where the message that is being sent to Slack can be confusing and not well understood. You can take the message provided to you from the notification and provide that as context to Q Developer to help you dive deep into the situation and help figure out next steps. To learn more about setting up notifications and having them be sent to your Slack, please refer to this documentation.
Figure 7 – Chatbot Error Notification
Figure 8 – Q Developer Deep Dive into Chatbot Notification
Architecture Diagram
Figure 9 – Solution Overview
A user logs into Slack and can either ask a question, run AWS command(s), or open a support case.
Slack sends the request to Chatbot which then validates that it can be processed from the channel role and associated guardrail policies, both of which are setup through AWS Identity and Access Management. If the request follows the Chatbot use case(s), we can disregard step 3 and move to step 4.
The request is forwarded to Q Developer where it is processed and formulates a response which is then sent back to Chatbot. Chatbot will then relay the response back to Slack which is displayed to the user.
Logs are captured from the original message and the response and can be located within Amazon CloudWatch
Next Steps
Refer to these AWS documentation links that cover how to get started with setting up Q Developer and Chatbot in Slack. It is important to follow the order of the listed documents and to adhere to each of the steps listed to be able to get started with using the solution.
AWS Chatbot Getting Started documentation outlines the steps to set up AWS Chatbot for interacting with AWS infrastructure. It covers steps such as setting up an AWS account, configuring IAM permissions, and setting up Amazon SNS topics for notifications.
This documentation shows how to integrate AWS Chatbot with Slack, enabling AWS notifications and interactions in Slack channels. It covers Slack client and channel configuration and testing notifications from AWS services to Slack. Once completed with setting up Slack with Chatbot, refer back to the main Chatbot documentation where you can additional links on monitoring AWS services, customizing Chatbot and performing CLI commands on the lefthand side.
After following the previous documentation steps,you can now integrate Amazon Q Developer with AWS Chatbot in Slack, allowing users to ask questions about AWS services directly in chat. It includes IAM role setup with managed policies and necessary configuration steps. Once completed, this will allow you to use Q Developer through Chatbot’s interface on Slack.
Conclusion
This post highlights how using Q Developer and Chatbot within Slack can boost productivity for a number of use cases. Individuals, teams, and organizations can use these two services’ capabilities to navigate the intricacies of AWS, troubleshoot ongoing issues, and provide real-time guidance all without leaving the familiarity of Slack.
As customers increasingly seek to harness the power of generative AI (GenAI) and machine learning to deliver cutting-edge applications, the need for a flexible, intuitive, and scalable development platform has never been greater. In this landscape, Streamlit has emerged as a standout tool, making it easy for developers to prototype, build, and deploy GenAI-powered apps with minimal friction. It is an open-source Python framework designed to simplify the development of custom web applications for data science, machine learning, and GenAI projects. With Streamlit, developers can quickly transform Python scripts into interactive dashboards, LLM-powered chatbots, and web apps, using just a few lines of code. Its unique combination of simplicity, interactivity, and speed is the perfect complement to the rapid advancements in AI.
When deploying Streamlit applications, customers often face the challenge of ensuring their applications are highly available and can scale to meet a variable amount of demand. To achieve these goals, customers are looking at serverless approaches to deploying their Streamlit apps. With a serverless application, you only pay for the resources required and do not want have to worry about managing servers or capacity planning.
In this post, we will walk you through deploying containerized, serverless Streamlit applications automatically via HashiCorp Terraform, an Infrastructure as Code (IaC) tool that enables users to define and provision infrastructure across cloud platforms.
Solution Overview
For this solution, we have the Streamlit app running on an Amazon Elastic Container Service (ECS) cluster across multiple availability zones (AZs), using AWS Fargate to manage the compute. Fargate is a serverless, pay-as-you-go compute engine that lets you focus on building apps without managing servers. Using Fargate helps reduce the undifferentiated heavy lifting that can come with building and maintaining web applications. It is also often desirable to use a Content Delivery Network (CDN) to ensure low latency for users globally by caching the content at edge locations closer to where the users are geographically located.
Let’s zoom in on the two architectures – the Streamlit App hosting architecture, and the Streamlit App deployment pipeline.
Streamlit app hosting
In the above architecture, the following flow applies:
Users access the Streamlit App using the public DNS endpoint for an Amazon CloudFront distribution.
Using an Internet Gateway (IGW), user requests are routed to a public-facing Application Load Balancer (ALB).
This ALB has target groups which map to ECS task nodes that are part of an ECS cluster running in two AZs (us-east-1a and us-east-1b in this example).
Fargate will automatically scale the underlying compute nodes in the ECS cluster based on the demand.
Streamlit app deployment pipeline
In the above architecture, the following flow applies:
User develops a local Streamlit App and defines the path of these assets in the module configuration, then runs terraform apply to generate a local .zip file comprised of the Streamlit App directory, and upload this to an Amazon S3 bucket (Streamlit Assets) with versioning enabled, which is configured to trigger the Streamlit CI/CD pipeline to run.
AWS CodePipeline (Streamlit CI/CD pipeline) begins running. The pipeline copies the .zip file from the Streamlit Assets S3 Bucket, stores the contents in a connected CodePipeline Artifacts S3 bucket, and passes the asset to the AWS CodeBuild project that is also part of the pipeline.
CodeBuild (Streamlit CodeBuild Project) configures a compute/build environment and fetches a Python Docker Image from a public Amazon ECR repository. CodeBuild uses Docker to build a new Streamlit App image based on what is defined in the Dockerfile within the .zip file, and pushes the new image to a private ECR repository. It tags the image with latest, an app_version (user-defined in Terraform), as well as the S3 Version ID of the .zip file and pushes the image to ECR.
ECS has a task definition that references the image in ECR based on the S3 Version ID tag which will always be a unique value, as it is generated whenever a new version of the file is created. This also serves as data lineage so versions of the Streamlit App .zip files in S3 can be linked to versions of the image stored in ECR. Once a new image is pushed to ECR (with a unique image tag), the task definition is updated and the ECS service begins a new deployment using the new version of the Streamlit App.
When a new image is pushed to ECR, the Terraform Module is configured to use the local-exec provisioner to run an AWS CLI command that creates a CloudFront invalidation. This enables users of the Streamlit app to use the new version without waiting for the time-to-live (TTL) of the cached file to expire on the edge locations (default is 24 hours). Both of these pipelines are built and packaged into a Terraform module that can be reused efficiently with only a few lines of code.
Both of these pipelines are built and packaged into a Terraform module that can be reused efficiently with only a few lines of code.
Prerequisites
This solution requires the following prerequisites:
An AWS account. If you don’t have an account, you can sign up for one.
Terraform v1.0.0 or newer installed.
python v3.8 or newer installed.
A Streamlit app. If you don’t have a Streamlit project already, you can download this app directory as a sample Streamlit app for this post and save it to a local folder.
Your folder structure will look something like this:
In the same folder where you have the your Streamlit app saved, in the above example in the terraform_streamlit_folder, you will create and initialize a new Terraform project.
In your preferred terminal, create a new file named main.tf by running the following command on Unix/Linux machines, or an equivalent command on Windows machines:
touch main.tf
Open up the main.tf file and add the following code to it:
module "serverless-streamlit-app" {
  source          = "aws-ia/serverless-streamlit-app/aws"
  app_name        = "streamlit-app"
  app_version     = "v1.1.0"
  path_to_app_dir = "./app" # Replace with path to your app
}
This code utilizes a module block with a source pointing to the Terraform module, and the appropriate input variables passed in. When Terraform encounters a module block, it loads and processes that module’s configuration files using the source. The Serverless Streamlit App Terraform module has many optional input variables. If you have existing resources, such as an existing VPC, subnets, and security groups that you’d like to reuse instead of deploying new ones, you can use the module’s input variables to reference your existing resources. However, in this post, we’re deploying all of the resources in the above architecture from scratch. Here, we simply define the source that references the module hosted in the Terraform Registry, provide an app_name that will be used as a prefix for naming your resources, the app_version that is used for tracking changes to your app, and the path_to_app_dir which is the path to the local directory where the assets for your Streamlit app are stored.
Save the file.
To initialize the Terraform working directory, run the following command in your terminal:
terraform init
The output will contain a successful message like the following:
"Terraform has been successfully initialized"
Output the CloudFront URL
To be able to easily access the Cloudfront URL of the deployed Streamlit application, you can add the URL as a Terraform output.
In your terminal, create a new file named outputs.tf by running the following command on Unix/Linux machines, or an equivalent command on Windows machines:
touch outputs.tf
Open up the outputs.tf file and add the following code to it:
output "streamlit_cloudfront_distribution_url" {
  value = module.serverless-streamlit-app.streamlit_cloudfront_distribution_url
}
Save the file. Now, your folder structure will look like:
Now you can use Terraform to deploy the resources defined in your main.tf file.
In your terminal, run the following command to apply to deploy the infrastructure. This includes the hosting for your Streamlit application using ECS and CloudFront, as well as the pipeline that is used to push updates.
terraform apply
When the apply command finishes running, you’ll see the Terraform outputs displayed in the terminal.
Navigate to the streamlit_cloudfront_distribution_url to see your Streamlit application that is hosted on AWS.
When you make changes to your Streamlit codebase, you can go ahead and re-run terraform apply to push your new changes to your cloud environment.
When updating the Streamlit codebase, the CodePipeline and CodeBuild processes kick off to automatically update your new changes, which get reflected on your Streamlit application. CodePipeline automates the entire software release process, managing stages like source retrieval, building, testing, and deployment. It integrates with AWS services and third-party tools (such as GitHub and Jenkins) to enhance automation, speed, and security. CodeBuild focuses on automating code compilation, testing, and packaging, supporting multiple languages and custom Docker environments, while integrating with CodePipeline for scalable, secure builds. With this CI/CD pipeline, when you make changes to your code, all you need to run is terraform apply to update your cloud environment. For an example buildspec, see the example in the repo.
You can find full examples of deploying the infrastructure with and without existing resources in the GitHub repository.
Clean up
When you no longer need the resources deployed in this post, you can clean up the resources by using the Terraform destroy command. Simply run terraform destroy . This will remove all of the resources you have deployed in this post with Terraform.
Conclusion
Building serverless Streamlit applications with Terraform on AWS offers a powerful combination of scalability, efficiency, and automation. As you continue to build and refine your Streamlit applications, Terraform’s flexibility ensures that your infrastructure can evolve seamlessly, supporting rapid innovation and agile development. With Streamlit and Terraform, you have the tools to create dynamic, serverless applications that scale effortlessly and operate reliably in the cloud.
As organizations increasingly adopt Amazon Q Developer, understanding how developers use it is essential. Diving into specific telemetry events and user-level data clarifies how users interact with Amazon Q Developer, offering insights into feature usage and developer behaviors. This granular view, accessible through logs, is vital for identifying trends, optimizing performance, and enhancing the overall developer experience. This blog is intended to give visibility to key telemetry events logged by Amazon Q Developer and how to explore this data to gain insights.
To help you get started, the following sections will walk through several practical examples that showcase how to extract meaningful insights from AWS CloudTrail. By reviewing the logs, organizations can track usage patterns, identify top users, and empower them to train and mentor other developers, ultimately fostering broader adoption and engagement across teams.
Although the examples here focus on Amazon Athena for querying logs, the methods can be adapted to integrate with other tools like Splunk or Datadog for further analysis. Through this exploration, readers will learn how to query the log data to understand better how Amazon Q Developer is used within your organization.
Solution Overview
This solution leverages Amazon Q Developer’s logs from the Integrated Development Environment (IDE) and terminal, captured in AWS CloudTrail. The logs will be queried directly using Amazon Athena from Amazon Simple Storage Service (Amazon S3) to analyze feature usage, such as in-line code suggestions, chat interactions, and security scanning events.
Analyzing Telemetry Events in Amazon Q Developer
Amazon Athena is used to query the CloudTrail logs directly to analyze this data. By utilizing Athena, queries can be run on existing CloudTrail records, making it simple to extract insights from the data in its current format.
Ensuring CloudTrail is set up to log the data events.
Navigate to the AWS CloudTrail Console.
Edit an Existing Trail:
If you have a trail, verify it is configured to log data events for Amazon CodeWhisperer.
Note: As of 4/30/24, CodeWhisperer has been renamed to Amazon Q Developer. All the functionality previously provided by CodeWhisperer is now part of Amazon Q Developer. However, for consistency, the original API names have been retained.
Click on your existing trail in CloudTrail. Find the Data Events section and click edit.
For CodeWhisperer:
Data event type: CodeWhisperer
Log selector template: Log all events
Save your changes.
Note your “Trail log location.” This S3 bucket will be used in our Athena setup.
If you don’t have an existing trail, follow the instructions in the AWS CloudTrail User Guide to set up a new trail.
Below is a screenshot of the data events addition:
Steps to Create an Athena Table from CloudTrail Logs: This step aims to turn CloudTrail events into a queryable Athena table.
1. Navigate to the AWS Management Console > Athena > Editor.
2. Click on the plus to create a query tab.
3. Run the following query to create a database and table. Note to update the location to your S3 bucket.
-- Step 1: Create a new database (if it doesn't exist)
CREATE DATABASE IF NOT EXISTS amazon_q_metrics;

-- Step 2: Create the external table explicitly within the new database
CREATE EXTERNAL TABLE amazon_q_metrics.cloudtrail_logs (

    userIdentity STRUCT<
        accountId: STRING,
        onBehalfOf: STRUCT<
            userId: STRING,
            identityStoreArn: STRING
        >
    >,
    eventTime STRING,
    eventSource STRING,
    eventName STRING,
    requestParameters STRING,
    requestId STRING,
    eventId STRING,
    resources ARRAY<STRUCT<
        arn: STRING,
        accountId: STRING,
        type: STRING
    >>,
    recipientAccountId STRING

)
ROW FORMAT SERDE 'org.apache.hive.hcatalog.data.JsonSerDe'
STORED AS INPUTFORMAT 'com.amazon.emr.cloudtrail.CloudTrailInputFormat'
OUTPUTFORMAT 'org.apache.hadoop.hive.ql.io.HiveIgnoreKeyTextOutputFormat'
LOCATION 's3://{Insert Bucket Name from CloudTrail}/'
TBLPROPERTIES ('classification'='cloudtrail');
4. Click Run
5. Run a quick query to view the data.
SELECT
    eventTime,
    userIdentity.onBehalfOf.userId AS user_id,
    eventName,
    requestParameters
FROM
    amazon_q_metrics.cloudtrail_logs AS logs
WHERE
    eventName = 'SendTelemetryEvent'
LIMIT 10;
In this section, the significance of the telemetry events captured in the requestParameters field will be explained. The query begins by displaying key fields and their data, offering insights into how users interact with various features of Amazon Q Developer.
Query Breakdown:
eventTime: This field captures the time the event was recorded, providing insights into when specific user interactions took place.
userIdentity.onBehalfOf.userId: This extracts the userId of the user. This is critical for attributing interactions to the correct user, which will be covered in more detail later in the blog.
eventName: The query is filtered on SendTelemetryEvent. Telemetry events are triggered when the user interacts with particular features or when a developer uses the service.
requestParameters: The requestParameters field is crucial because it holds the details of the telemetry events. This field contains a rich set of information depending on the type of interaction and feature the developer uses, which programming languages are used, completion types, or code modifications.
In the context of the SendTelemetryEvent, various telemetry events are captured in the requestParameters field of CloudTrail logs. These events provide insights into user interactions, overall usage, and the effectiveness of Amazon Q Developer’s suggestions. Here are the key telemetry events along with their descriptions:
UserTriggerDecisionEvent
Description: This event is triggered when a user interacts with a suggestion made by Amazon Q Developer. It captures whether the suggestion was accepted or rejected, along with relevant metadata.
Key Fields:
completionType: Whether the completion was a block or a line.
suggestionState: Whether the user accepted, rejected, or discarded the suggestion.
programmingLanguage: The programming language associated with the suggestion.
generatedLine: The number of lines generated by the suggestion.
CodeScanEvent
Description: This event is logged when a code scan is performed. It helps track the scope and result of the scan, providing insights into security and code quality checks.
Key Fields:
codeAnalysisScope: Whether the scan was performed at the file level or the project level.
programmingLanguage: The language being scanned.
CodeScanRemediationsEvent
Description: This event captures user interactions with Amazon Q Developer’s remediation suggestions, such as applying fixes or viewing issue details.
Key Fields:
CodeScanRemediationsEventType: The type of remediation action taken (e.g., viewing details or applying a fix).
includesFix: A boolean indicating whether the user applied a fix.
ChatAddMessageEvent
Description: This event is triggered when a new message is added to an ongoing chat conversation. It captures the user’s intent which refers to the purpose or goal the user is trying to achieve with the chat message. The intent can include various actions, such as suggesting alternate implementations of the code, applying common best practices, improving the quality or performance of the code.
Key Fields:
conversationId: The unique identifier for the conversation.
messageId: The unique identifier for the chat message.
userIntent: The user’s intent, such as improving code or explaining code.
programmingLanguage: The language related to the chat message.
ChatInteractWithMessageEvent
Description: This event captures when users interact with chat messages, such as copying code snippets, clicking links, or hovering over references.
Key Fields:
interactionType: The type of interaction (e.g., copy, hover, click).
interactionTarget: The target of the interaction (e.g., a code snippet or a link).
acceptedCharacterCount: The number of characters from the message that were accepted.
acceptedSnippetHasReference: A boolean indicating if the accepted snippet included a reference.
TerminalUserInteractionEvent
Description: This event logs user interactions with terminal commands or completions in the terminal environment.
Key Fields:
terminalUserInteractionEventType: The type of interaction (e.g., terminal translation or code completion).
isCompletionAccepted: A boolean indicating whether the completion was accepted by the user.
terminal: The terminal environment in which the interaction occurred.
shell: The shell used for the interaction (e.g., Bash, Zsh).
Telemetry events are key to understanding how users engage with Amazon Q Developer. They track interactions such as code completion, security scans, and chat-based suggestions. Analyzing the data in the requestParameters field helps reveal usage patterns and behaviors that offer valuable insights.
By exploring events such as UserTriggerDecisionEvent, ChatAddMessageEvent, TerminalUserInteractionEvent, and others in the schema, organizations can assess the effectiveness of Amazon Q Developer and identify areas for improvement.
Example Queries for Analyzing Developer Engagement
To gain deeper insights into how developers interact with Amazon Q Developer, the following queries can help analyze key telemetry data from CloudTrail logs. These queries track in-line code suggestions, chat interactions, and code-scanning activities. By running these queries, you can uncover valuable metrics such as the frequency of accepted suggestions, the types of chat interactions, and the programming languages most frequently scanned. This analysis helps paint a clear picture of developer engagement and usage patterns, guiding efforts to enhance productivity.
These four examples only cover a sample set of the available telemetry events, but they serve as a starting point for further exploration of Amazon Q Developer’s capabilities.
SELECT
    eventTime,
    userIdentity.onBehalfOf.userId AS user_id,
    eventName,
    json_extract_scalar(requestParameters, '$.telemetryEvent.userTriggerDecisionEvent.suggestionState') AS suggestionState,
    json_extract_scalar(requestParameters, '$.telemetryEvent.userTriggerDecisionEvent.completionType') AS completionType
FROM
    amazon_q_metrics.cloudtrail_logs
WHERE
    eventName = 'SendTelemetryEvent'
    AND json_extract(requestParameters, '$.telemetryEvent.userTriggerDecisionEvent') IS NOT NULL
    AND json_extract_scalar(requestParameters, '$.telemetryEvent.userTriggerDecisionEvent.suggestionState') = 'ACCEPT';
Use Case:This use case focuses on how developers interact with in-line code suggestions by analyzing accepted snippets. It helps identify which users are accepting suggestions, the type of snippets being accepted (blocks or lines), and the programming languages involved. Understanding these patterns can reveal how well Amazon Q Developer aligns with the developers’ expectations.
Query Explanation: The query retrieves the event time, user ID, event name, suggestion state (filtered to show only ACCEPT), and completion type. TotalGeneratedLinesBlockAccept and totalGeneratedLinesLineAccept or discarded suggestions are not included, but this gives an idea of the developers using the service for in-line code suggestions and the lines or blocks they have accepted. Additionally, the programming language field can be extracted to see which languages are used during these interactions.
Query 2: Analyzing Chat Interactions
SELECT
    userIdentity.onBehalfOf.userId AS userId,
    json_extract_scalar(requestParameters, '$.telemetryEvent.chatInteractWithMessageEvent.interactionType') AS interactionType,
    COUNT(*) AS eventCount
FROM
    amazon_q_metrics.cloudtrail_logs
WHERE
    eventName = 'SendTelemetryEvent'
    AND json_extract(requestParameters, '$.telemetryEvent.chatInteractWithMessageEvent') IS NOT NULL
GROUP BY
    userIdentity.onBehalfOf.userId,
    json_extract_scalar(requestParameters, '$.telemetryEvent.chatInteractWithMessageEvent.interactionType')
ORDER BY
    eventCount DESC;
Use Case: This use case looks at how developers use chat options like upvoting, downvoting, and copying code snippets. Understanding the chat usage patterns shows which interactions are most used and how developers engage with Amazon Q Developer chat. As an organization, this insight can help support other developers in successfully leveraging this feature.
Query Explanation: The query provides insights into chat interactions within Amazon Q Developer by retrieving user IDs, interaction types, and event counts. This query aggregates data based on the interactionType field within chatInteractWithMessageEvent, showcasing various user actions such as UPVOTE, DOWNVOTE, INSERT_AT_CURSOR, COPY_SNIPPET, COPY, CLICK_LINK, CLICK_BODY_LINK, CLICK_FOLLOW_UP, and HOVER_REFERENCE.
This analysis highlights how users engage with the chat feature and the interactions, offering a view of interaction patterns. By focusing on the interactionType field, you can better understand how developers interact with the chat feature of Amazon Q Developer.
Query 3: Analyzing Code Scanning Jobs Across Programming Languages
SELECT
    userIdentity.onBehalfOf.userId AS userId,
    json_extract_scalar(requestParameters, '$.telemetryEvent.codeScanEvent.programmingLanguage.languageName') AS programmingLanguage,
    COUNT(json_extract_scalar(requestParameters, '$.telemetryEvent.codeScanEvent.codeScanJobId')) AS jobCount
FROM
    amazon_q_metrics.cloudtrail_logs
WHERE
    eventName = 'SendTelemetryEvent'
    AND json_extract(requestParameters, '$.telemetryEvent.codeScanEvent') IS NOT NULL
GROUP BY
    userIdentity.onBehalfOf.userId,
    json_extract_scalar(requestParameters, '$.telemetryEvent.codeScanEvent.programmingLanguage.languageName')
ORDER BY
    jobCount DESC;
Use Case: Amazon Q Developer includes security scanning, and this section helps determine how the security scanning feature is being used across different users and programming languages within the organization. Understanding these trends provides valuable insights into which users actively perform security scans and the specific languages targeted for these scans.
Query Explanation: The query provides insights into the distribution of code scanning jobs across different programming languages in Amazon Q Developer. It retrieves user IDs and the count of code-scanning jobs by programming language. This analysis focuses on the CodeScanEvent, aggregating data to show the total number of jobs executed per language.
By summing up the number of code scanning jobs per programming language, this query helps to understand which languages are most frequently analyzed. It provides a view of how users are leveraging the code-scanning feature. This can be useful for identifying trends in language usage and optimizing code-scanning practices.
Query 4: Analyzing User Activity across features.
SELECT
    userIdentity.onBehalfOf.userId AS user_id,
    COUNT(DISTINCT CASE
        WHEN json_extract(requestParameters, '$.telemetryEvent.userTriggerDecisionEvent') IS NOT NULL
        THEN eventId END) AS inline_suggestions_count,
    COUNT(DISTINCT CASE
        WHEN json_extract(requestParameters, '$.telemetryEvent.chatInteractWithMessageEvent') IS NOT NULL
        THEN eventId END) AS chat_interactions_count,
    COUNT(DISTINCT CASE
        WHEN json_extract(requestParameters, '$.telemetryEvent.codeScanEvent') IS NOT NULL
        THEN eventId END) AS security_scans_count,
    COUNT(DISTINCT CASE
        WHEN json_extract(requestParameters, '$.telemetryEvent.terminalUserInteractionEvent') IS NOT NULL
        THEN eventId END) AS terminal_interactions_count
FROM
    amazon_q_metrics.cloudtrail_logs
WHERE
    eventName = 'SendTelemetryEvent'
GROUP BY
    userIdentity.onBehalfOf.userId
Use Case:This use case looks at how developers use Amazon Q Developer across different features: in-line code suggestions, chat interactions, security scans, and terminal interactions. By tracking usage, organizations can see overall engagement and identify areas where developers may need more support or training. This helps optimize the use of Amazon Q Developer and helps teams get the most out of the tool.
Query Explanation: Let’s take the other events from the prior queries and additional events to get more detail overall and tie it all together. This expanded query provides a comprehensive view of user activity within Amazon Q Developer by tracking the number of in-line code suggestions, chat interactions, security scans, and terminal interactions performed by each user. By analyzing these events, organizations can gain a better understanding of how developers are using these key features.
By summing up the interactions for each feature, this query helps identify which users are most active in each category, offering insights into usage patterns and areas where additional training or support may be needed.
Enhancing Metrics with Display Names and Usernames
The previous queries had userid as a field; however, many customers would prefer to see a user alias (such as username or display name). The following section illustrates enhancing these metrics by augmenting user IDs with display names and usernames from the AWS IAM Identity Center. This will provide more human-readable user names.
In this example, the export is run locally to enhance user metrics with IAM Identity Center for simplicity. This method works well for demonstrating how to access and work with the data, but it provides a static snapshot of the users at the time of export. In a production environment, an automated solution would be preferable to capture newly added users continuously. For the purposes of this blog, this straightforward approach is used to focus on data access.
To proceed, install Python 3.8+ and Boto3, and configure AWS credentials via the CLI. Then, run the following Python script locally to export the data:
import boto3, csv
# replace this with the region of your IDC instance
RegionName='us-east-1'
# client creation
idstoreclient = boto3.client('identitystore', RegionName)
ssoadminclient = boto3.client('sso-admin', RegionName)

Instances= (ssoadminclient.list_instances()).get('Instances')
InstanceARN=Instances[0].get('InstanceArn')
IdentityStoreId=Instances[0].get('IdentityStoreId')

# query
UserDigestList = []
ListUserResponse = idstoreclient.list_users(IdentityStoreId=IdentityStoreId)
UserDigestList.extend([[user['DisplayName'], user['UserName'], user['UserId']] for user in ListUserResponse['Users']])
NextToken = None
if 'NextToken' in ListUserResponse.keys(): NextToken = ListUserResponse['NextToken']
while NextToken is not None:
    ListUserResponse = idstoreclient.list_users(IdentityStoreId=IdentityStoreId, NextToken=NextToken)
    UserDigestList.extend([[user['DisplayName'], user['UserName'], user['UserId']] for user in ListUserResponse['Users']])
    if 'NextToken' in ListUserResponse.keys(): NextToken = ListUserResponse['NextToken']
    else: NextToken = None

# write the query results to IDCUserInfo.csv
with open('IDCUserInfo.csv', 'w') as CSVFile:
    CSVWriter = csv.writer(CSVFile, quoting=csv.QUOTE_ALL)
    HeaderRow = ['DisplayName', 'UserName', 'UserId']
    CSVWriter.writerow(HeaderRow)
    for UserRow in UserDigestList:
        CSVWriter.writerow(UserRow)
This script will query the IAM Identity Center for all users and write the results to a CSV file, including DisplayName, UserName, and UserId. After generating the CSV file, upload it to an S3 bucket. Please make note of this S3 location.
Steps to Create an Athena Table from the above CSV output: Create a table in Athena to join the existing table with the user details.
1. Navigate to the AWS Management Console > Athena > Editor.
2. Click on the plus to create a query tab.
3. Run the following query to create our table. Note to update the location to your S3 bucket.
CREATE EXTERNAL TABLE amazon_q_metrics.user_data (
    DisplayName STRING,
    UserName STRING,
    UserId STRING
)
ROW FORMAT SERDE 'org.apache.hadoop.hive.serde2.OpenCSVSerde'
WITH SERDEPROPERTIES (
   'separatorChar' = ',',
   'quoteChar'     = '"'
)
STORED AS TEXTFILE
LOCATION 's3://{Update to your S3 object location}/'  -- Path containing CSV file
TBLPROPERTIES ('skip.header.line.count'='1');
4. Click Run
5. Now, let’s run a quick query to verify the data in the new table.
SELECT * FROM amazon_q_metrics.user_data limit 10;
The first query creates an external table in Athena from user data stored in a CSV file in S3. The user_data table has three fields: DisplayName, UserName, and UserId. To specify the correct parsing of the CSV, separatorChar is specified as a comma and quoteChar as a double quote. Additionally, the TBLPROPERTIES (‘skip.header.line.count’=’1’) flag skips the header row in the CSV file, ensuring that column names aren’t treated as data.
The user_data table holds key details: DisplayName (full name), UserName (username), and UserId (unique identifier). This table will be joined with the cloudtrail_q_metrics table using the userId field from the onBehalfOf struct, enriching the interaction logs with human-readable user names and display names instead of user IDs.
In the previous analysis of in-line code suggestions, the focus was on retrieving key metrics related to user interactions with Amazon Q Developer. The query below follows a similar structure but now includes a join with the user_data table to enrich insights with additional user details such as DisplayName and Username.
To include a join with the user_data table in the query, it is necessary to define a shared key between the cloudtrail_logs_amazon_q and user_data tables. For this example, user_id will be used.
SELECT
    logs.eventTime,
    user_data.displayname,  -- Additional field from user_data table
    user_data.username,     -- Additional field from user_data table
    json_extract_scalar(logs.requestParameters, '$.telemetryEvent.userTriggerDecisionEvent.suggestionState') AS suggestionState,
    json_extract_scalar(logs.requestParameters, '$.telemetryEvent.userTriggerDecisionEvent.completionType') AS completionType
FROM
    amazon_q_metrics.cloudtrail_logs AS logs  -- Specified database for cloudtrail_logs
JOIN
    amazon_q_metrics.user_data  -- Specified database for user_data
ON
    logs.userIdentity.onBehalfOf.userId = user_data.userid
WHERE
    logs.eventName = 'SendTelemetryEvent'
    AND json_extract_scalar(logs.requestParameters, '$.telemetryEvent.userTriggerDecisionEvent.suggestionState') = 'ACCEPT';
This approach allows for a deeper analysis by integrating user-specific information with the telemetry data, helping you better understand how different user roles interact with the in-line suggestions and other features of Amazon Q Developer.
Cleanup
If you have been following along with this workflow, it is important to clean up the resources to avoid unnecessary charges. You can perform the cleanup by running the following query in the Amazon Athena console:
-- Step 1: Drop the tables
DROP TABLE IF EXISTS amazon_q_metrics.cloudtrail_logs;
DROP TABLE IF EXISTS amazon_q_metrics.user_data;

-- Step 2: Drop the database after the tables are removed
DROP DATABASE IF EXISTS amazon_q_metrics CASCADE;
This query removes both the cloudtrail_logs and user_data tables, followed by the amazon_q_metrics database.
Remove the S3 objects used to store the CloudTrail logs and user data by navigating to the S3 console, selecting the relevant buckets or objects, and choosing “Delete.”
If a new CloudTrail trail was created, consider deleting it to stop further logging. For instructions, see Deleting a Trail. If an existing trail was used, remove the CodeWhisperer data events to prevent continued logging of those events.
Conclusion
By tapping into Amazon Q Developer’s logging capabilities, organizations can unlock detailed insights that drive better decision-making and boost developer productivity. The ability to analyze user-level interactions provides a deeper understanding of how the service is used.
Now that you have these insights, the next step is leveraging them to drive improvements. For example, organizations can use this data to identify opportunities for Proof of Concepts (PoCs) and pilot programs that further demonstrate the value of Amazon Q Developer. By focusing on areas where engagement is high, you can support the most engaged developers as champions to advocate for the tool across the organization, driving broader adoption.
The true potential of these insights lies in the “art of the possible.” With the data provided, it is up to you to explore how to query or visualize it further. Whether you’re examining metrics for in-line code suggestions, interactions, or security scanning, this foundational analysis is just the beginning.
As Amazon Q Developer continues to evolve, staying updated with emerging telemetry events is crucial for maintaining visibility into the available metrics. You can do this by regularly visiting the official Amazon Q Developer documentation and the Amazon Q Developer’s Changelog to stay up-to-date latest information and insights.
Amazon CodeCatalyst is a unified service that streamlines the entire software development lifecycle, empowering teams to build, deliver, and scale applications on AWS.
DevSecOps is the practice of integrating security into all stages of software development. Rather than prioritizing features, it injects security into an earlier phase of the development process – baking it into design, coding, testing, deployment, and operations from the start. Extensive automation like policy checks, scanning, and more proactively uncovers risks.
Amazon Inspector Scan is a CodeCatalyst Action, a logical unit of work to be performed during a workflow run, which leverages software bill of materials (SBOM) generator (sbomgen) to produce a SBOM and ScanSbom to scan a provided CycloneDX 1.5 SBOM and report on any vulnerabilities discovered in that SBOM. An SBOM inventories third-party and open-source components in an application, documenting names, versions, licenses, dependencies, and more. It enables vital DevSecOps initiatives, such as checking an SBOM against CVE databases to rapidly identify vulnerable libraries needing remediation.
Introduction
This blog talks about the benefits of DevSecOps in general and the SBOM in particular. It provides a walkthrough of adding SBOM generation and scanning as a CodeCatalyst Action to an existing CodeCatalyst Workflow. A workflow is an automated procedure that describes how to build, test, and deploy your code as part of a CI/CD system. First, you will create a new Amazon CodeCatalyst project in the CodeCatalyst console. Next, you will modify the workflow to add the Amazon Inspector Scan action. Lastly, you will run the workflow and view the SBOM and vulnerabilities report.
An AWS Identity and Access Management (IAM) role (that will be added to the Amazon CodeCatalyst space later) to provide Amazon CodeCatalyst service permissions to build and deploy applications.
First, you will create a project using CodeCatalyst Blueprints. Blueprints setup a code repository with a working sample app, define cloud infrastructure and run pre-configured CI/CD workflows for your project.
Create a project from a blueprint
Go to your space by clicking your space name in the CodeCatalyst console. From your space, click Create Project. Upon selecting Start with a blueprint, you will select the Single-page application blueprint and click Next as shown in figure 1.
You will then pick a suitable name for your project, for this post I will use SafeWebShip. Select the AWS IAM role associated with the space and account connection, then click on Create Project.
Next, you will take a look at the current workflow and add the Amazon Inspector Scan action to identify the packages and libraries that make up a software application and scan for vulnerabilities from the associated packages and libraries.
Review the current workflow
A workflow defines a series of steps, or actions, to take during a workflow run and can be assembled using YAML or a visual editor. Actions which require interaction with AWS resources like creation, modification, reading, and deletion occur in the customer’s AWS account, such as creating an Amazon Inspector task to scan an SBOM report.
Add SBOM generation and scanning to the workflow
To add the Amazon Inspector Scan action to the workflow:
Navigate to the CI/CD menu on the left side of your screen, and then click Workflows
Click on the onPushToMainPipeline workflow
Click the edit button to make changes to the workflow
Ensure the Visual tab is selected, then add a CodeCatalyst Action by clicking Actions at the top left of the screen
In the new Actions catalog pop-up, search Amazon Inspector Scan. Click the + at the bottom right of the action card as shown in figure 2
Figure 2 Amazon CodeCatalyst Actions Catalog
Click the Configuration tab of the action and rename the action to inspector_sbom by clicking the pencil under action name
Select the environment from the Environment dropdown, AWS account connection and the Role you created earlier in the pre-requisite
Scroll down to Path and ensure it is “./” which represents the root of the source repository. The tool will traverse all of the directories of the source repository for supported manifest files to scan
The Scan Source should be REPO. The action can scan directories or source repository and a container image. For the purpose of this blog, you will be scanning an existing source repository
The tool can be configured to run scanners that will inspect container images, packages, archive, directory, and binary scanners. For the purpose of this blog, you will be using javascript-nodejs scanner. You can skip the rest of the scanners. You can read the action’s documentation from the action’s catalog page for a full list of supported scanners
Scroll down to Severity Threshold, type medium to fail the action if a vulnerability of medium or greater is found
Skip Files determines the files to skip and should be public/ since you are scanning a public repository
Depth specifies the depth of directory traversal when generating the SBOM. You should pick Depth as 1 to scan all the files in the root directory of the public repository. Other inputs that are relevant to container images can be ignored as the source repository is only being scanned
The action produces two files, the SBOM in CycloneDX v1.5 format from sbomgen and the vulnerability report from ScanSbom. Click the Outputs tab of the action, under Artifacts click Add artifact
Name the Build artifact name as SBOM
Paste the Files produced by build with the followinginspector_sbom_report.json
Click Add artifact again
Name the Build artifact name as SBOM_VULNERABILITIES
Paste the Files produced by build with the following
inspector_scan_report.json
Figure 3 Amazon CodeCatalyst Workflow Screen
As a best practice, you don’t want to build your project unless it has passed the security scan.
Do the following:
From the visual diagram of the workflow, click the Build action
With new menu pop-up to the right, in the pre-loaded inputs tab, and under Depends on – optional, select the Add actions dropdown menu and select the inspector_sbom action
Click x next to the action name to leave the action input menu
Finally, in order to save our changes to the workflow do the following:
Click Validate
Once you see a banner at the top of the page that says the workflow definition is valid, click Commit then click Commit once more to publish the changes to the workflow.
Run the workflow and view artifacts
After committing your changes to the workflow. There should be a new workflow run automatically as the trigger to the workflow is a code push.
Currently, SBOM CycloneDX v1.5 is not supported via CodeCatalyst Reports. Therefore, the report can not be visualized under the Reports feature of Amazon CodeCatalyst. However, the SBOM in CycloneDX v1.5 and the scan report are provided as artifacts for you to download and are stored as part of a workflow run.
To access the reports, do the following:
Navigate to the CI/CD menu on the left side of your screen, and then click Workflows
Click on the onPushToMainPipeline workflow
The current view is the Latest state, Click Runs
When the workflow, or CI/CD pipeline, runs, it is referred to as a run. Runs that are in progress are under Active runs and Runs history contains all previous workflow runs. Click the Run ID under latest run
Once the workflow run page loads, click Artifacts
On the Artifacts page, you should notice SBOM, CycloneDX v1.5, and SBOM_VULNERABILITIES, scan of the SBOM for vulnerabilities as shown in figure 4. Both of these artifacts can be downloaded and viewed on your local machine
The SBOM report will be downloaded as inspector_sbom_report.json. In the SBOM report, all the components that make up the software application are available to view. Each listed component is identified by its name and version as shown in figure 5.
Figure 5 Amazon Inspector Scan SBOM Artifact
The scan of the SBOM report for vulnerabilities will be downloaded as inspector_scan_report.json. In the scan report example below, there are 41 medium vulnerabilities and 32 high vulnerabilities. Since the threshold was set to “medium,” the build failed so these vulnerabilities can be addressed.
The scan report details the vulnerabilities, links to the affected components, and contains information on the vulnerability like description and CVE reference identifier as shown in figure 6 and figure 7.
Figure 7 Amazon Inspector Scan Vulnerability Artifact continued
Clean Up
If you have been following along with building this workflow, you should delete the resources you deployed so you do not continue to incur charges.
First, delete the stack titled DevelopmentFrontendStack-* that has been deployed from the AWS CloudFormation console in the AWS account you associated when you launched the blueprint. Second, delete the project from CodeCatalyst by navigating to Project settings and clicking the Delete project button
Conclusion
In this blog, we demonstrated how you can integrate security practices into a development pipeline using Amazon CodeCatalyst and Amazon Inspector. You created a project from a blueprint that came pre-configured with a workflow. Next, you modified the workflow to add DevSecOps practices to the pipeline through SBOM generation and scanning. Finally, you ran the workflow and viewed the SBOM and vulnerabilities report. It is essential to secure application dependencies during modern software development. For improved software supply chain security, Amazon CodeCatalyst and Amazon Inspector connect effortlessly. Add this action to your existing or new workflows to improve code security. This is necessary in today’s circumstances to protect your software supply chain. Learn more about Amazon CodeCatalyst and get started today!
As organizations continue to embrace cloud-native development practices, the need for integrated security solutions that seamlessly fit into existing DevOps environments has become more pressing than ever. We recognize this critical need and have added new integration for InsightCloudSec (ICS) and Exposure Command with Azure DevOps for Infrastructure as code (IaC) tooling, empowering organizations to quickly and effectively safeguard their attack surfaces.
But first, let’s quickly refresh infrastructure as code functionality within ICS to remind us of how important it is and why this new integration will play a key role in your organization’s security posture. Shifting left in code security is more important than ever before and IaC is the impetus for organizations to move cloud security and compliance from being reactive (at runtime) to being preventative (during development). The key is integrating the right controls with the proper guidance directly into the CI/CD pipeline. This integration facilitates delivering secure and compliant cloud infrastructure from the start. Rapid7’s innovative IaC tool allows you to identify key insights and risks during the development process which allow you to protect and secure your attack surface before it’s visible. If you want to learn more about getting started with IaC you can check out this helpful guide.
Why DevSecOps is so important
In today’s fast-paced development environments, security cannot be an afterthought. The ability to integrate security checks directly into DevOps — commonly referred to as DevSecOps — workflows is crucial for minimizing vulnerabilities and reducing the risk of breaches.
Making security a shared responsibility between development, operations and security teams has a number of key benefits:
It enables developers to deliver better, more-secure code faster, and, therefore, cheaper.
It makes security a continuous activity, allowing for issues to be caught proactively before they reach production.
It stops an all-too-common dynamic where security teams are only being brought in at the end of the project process in a QA role.
Impact of the new integration
With cloud environments being dynamic and complex, it’s vital to have tools that can quickly scan repositories and return actionable insights with minimal disruption to the development process. This is where the integration between InsightCloudSec and Azure DevOps makes a significant impact. By embedding security directly into the CI/CD pipeline, organizations can ensure that their code is secure before it ever reaches production, thus safeguarding their entire attack surface more effectively
The integration of InsightCloudSec with Azure DevOps introduces a suite of new capabilities designed to enhance how organizations assess and respond to potential risks within their cloud environments.
Here’s how it transforms the security landscape:
Extend attack surface visibility Into the CI/CD pipeline: The integration is designed to maximize the protection of your cloud environment by continuously monitoring and assessing risks by shifting security controls to the left. By catching issues early, it significantly reduces the likelihood of security threats reaching production, thereby minimizing the potential attack surface.
Proactive repository scanning: With this integration, security scans are executed as a seamless part of the CI/CD pipeline. As soon as IaC templates are changed in version control systems, InsightCloudSec can automatically scan repositories, identifying vulnerabilities, misconfigurations, and compliance issues. This seamless execution ensures that security checks do not hinder development velocity, allowing teams to maintain their pace while ensuring security.
Frictionless risk assessment and remediation: Rapid7’s integration emphasizes ease of use, ensuring that security assessments and remediation steps are as frictionless as possible. Real-time alerts and detailed insights are provided directly within Azure DevOps, enabling teams to quickly understand and address risks without needing to navigate multiple tools. This streamlined approach not only speeds up the response time but also ensures that remediation efforts are effective and aligned with organizational security policies.
Improved collaboration between security and DevOps teams: Driving better integration between security tooling and the CI/CD pipeline helps break down the unfortunately all too common “us vs. them” mentality that can exist between development and security teams. By automating repeatable, time-consuming tasks, such as vulnerability scanning and compliance checks, teams can shift their focus away from manual, often reactive efforts, and towards proactive collaboration. This streamlined approach empowers developers to identify and remediate security issues early in the development process without slowing down delivery, while security professionals gain visibility into code changes in real-time. The result is a more cohesive, efficient workflow where both teams work together to address complex, impactful problems, rather than being bogged down by friction and misaligned priorities.
Integration benefits at-a-glance
The integration between Rapid7’s InsightCloudSec and Azure DevOps will help organizations using the Azure ecosystem of tools easily advance their cloud security programs by shifting left, offering organizations the tools they need to effectively safeguard their attack surfaces without slowing down their development processes. By doing so, organizations can proactively address risks before they become significant threats, leading to a more secure and resilient cloud environment.
Automated scans and seamless alerting within Azure DevOps reduce the time it takes to identify and remediate vulnerabilities, helping organizations maintain a rapid development cycle without sacrificing security. The integration also fosters improved collaboration between security and development teams, ensuring that security is a shared responsibility. With clear and actionable insights provided within the same environment developers use daily, security becomes an integral part of the DevOps workflow.
By delivering seamless, frictionless security assessments and remediation steps directly within the CI/CD pipeline, Rapid7 continues to empower organizations to build, deploy, and maintain secure cloud environments with confidence.
As organizations navigate the complexities of cloud security, this integration will be a vital asset in ensuring that their cloud environments remain secure, compliant, and resilient against ever-evolving threats. Be sure to stay tuned for more updates as we continue to invest in driving more seamless integration between security and development processes.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.


 Figure 4: CloudFormation troubleshooting with CloudTrail integration

 Figure 6: CloudFormation troubleshooting with Q feature


 Figure 9: IaC generator resource scan


 Figure 12: CloudFormation Hooks’ Lambda function feature

 Figure 14: CloudFormation Git sync with request review support feature


![] Response from Amazon Q for the breakdown of EC2 costs in the last month](https://d2908q01vomqb2.cloudfront.net/7719a1c782a1ba91c031a682a0a2f8658209adbf/2025/02/03/figure12.png)


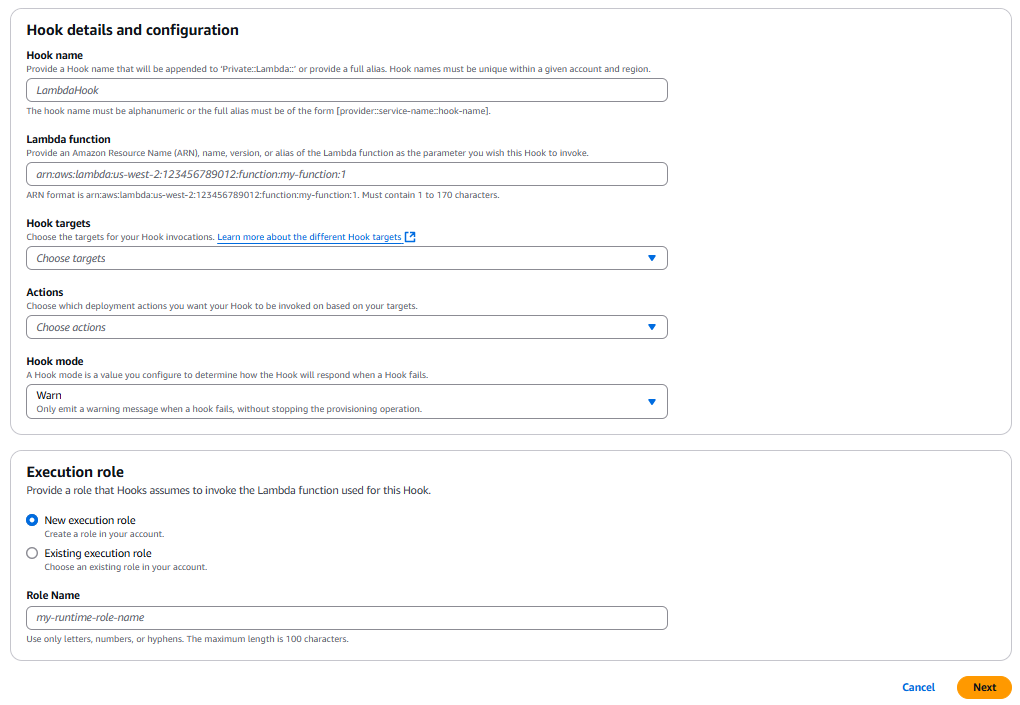


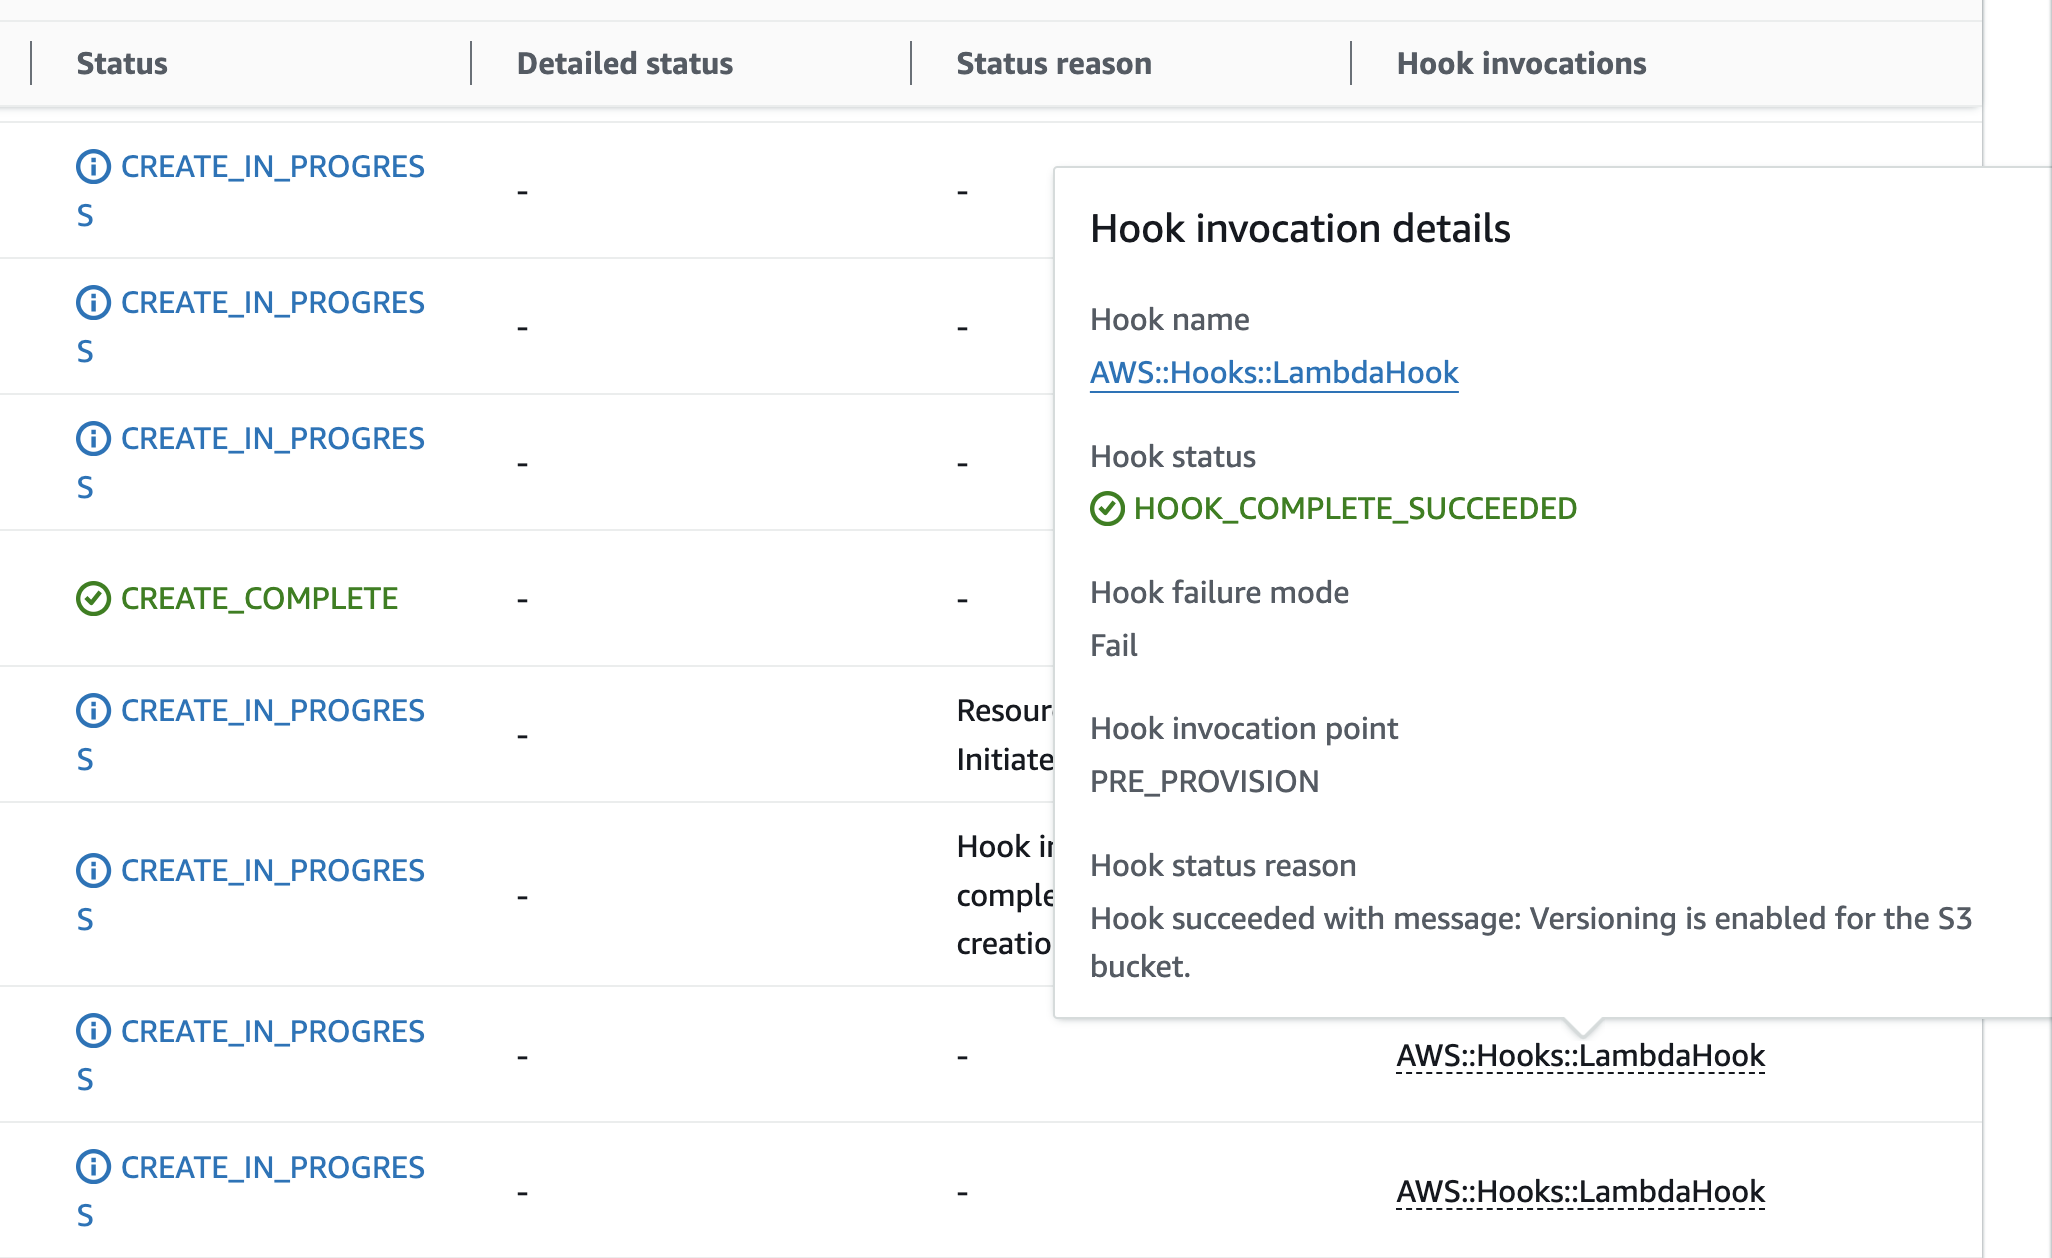

 Stella Hie is a Sr. Product Manager Technical for AWS Infrastructure as Code. She focuses on proactive control and governance space, working on delivering the best experience for customers to use AWS solutions safely. Outside of work, she enjoys hiking, playing piano, and watching live shows.


 Figure 3: CloudFormation’s create stack console wizard
 Figure 4: Real-time CloudFormation in-progress deployment timeline view

 Figure 6: CloudFormation completed deployment timeline view
 Figure 7: CloudFormation deployment timeline view – resource detail popover