Tag Archives: news

AWS Week in Review – Step Functions Versions and Aliases, EC2 Instances with Graviton3E Processors, and More – June 26, 2023

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/aws-week-in-review-step-functions-versions-and-aliases-ec2-instances-with-graviton3e-processors-and-more-june-26-2023/

It’s now summer in the northern hemisphere, and you can feel it in London where I live. But let’s not get distracted by the nice weather and go through your AWS updates from the previous seven days.

Last Week’s Launches
Another interesting week with many announcements! Here are some that got more of my attention:

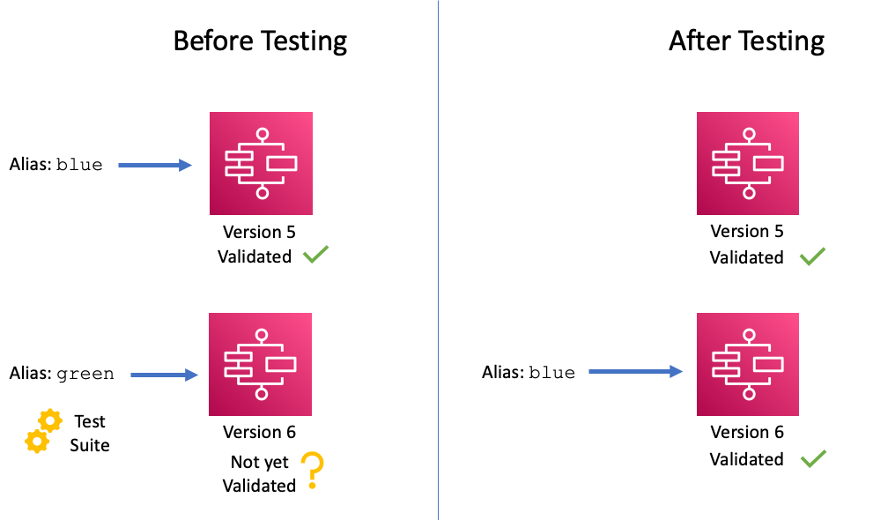
Architectural diagram for AWS Step Functions versioning and aliasesAWS Step Functions – You can now use versions and aliases to maintain multiple versions of your workflows, track which version was used for each execution, and create aliases that route traffic between workflow versions. To learn more, refer to this blog post.

AWS SAM – You can now simplify the way you define an AppSync GraphQL API in AWS SAM with the new a resource abstraction that includes everything necessary for a typical AppSync GraphQL API definition, including the API schema, the resolver pipeline functions, and data sources.

AWS Amplify – With the new Amplify UI Builder Figma plugin, you can theme your components, upgrade to new Amplify UI kit versions, and generate and preview React code from your designs directly in Figma.

AWS Local Zones – Now available in Manila, Philippines. You can use AWS Local Zones for applications that require single-digit millisecond latency or local data processing.

AWS Control Tower – The integration with Security Hub is now generally available. You can now enable over 170 Security Hub detective controls that map to related control objectives from AWS Control Tower. AWS Control Tower also detects drifts when you disable a control from Security Hub.

Amazon Kinesis Data Firehose – You can now deliver streaming data to Amazon Redshift Serverless. In this way, you can build an analytics platform without having to manage ingestion infrastructure or data warehouse clusters.

Amazon CloudWatch Internet Monitor – Now available in all standard AWS Regions. Internet Monitor helps you diagnose internet issues between your AWS hosted applications and your application’s end users.

AWS Verified Access – Now provides improved logging functionality. With that, It’s easier to author and troubleshoot application access policies by reviewing the end-user context received from third-party services.

Amazon Managed Grafana – Now supports Trace Analytics with the OpenSearch Grafana data source plugin in addition to the existing support for Log Analytics. You can simplify the correlation and analysis of logs and trace data stored in OpenSearch along with metrics from other data sources.

Amazon CloudWatch Logs Insights – You can now use the new dedup command in your queries to view unique results based on one or more fields. Duplicates are discarded based on the sort order so that only the first result is kept.

AWS Config – Now supports 21 more resource types for services such as AWS Amplify, AWS App Mesh, AWS App Runner, Amazon Kinesis Data Firehose, and Amazon SageMaker.

Amazon EC2 – Announcing the new EC2 C7gn and Hpc7g instances that use Graviton3E processors. The Graviton3E processor delivers higher memory bandwidth and compute performance than Graviton2, and higher vector instruction performance than Graviton3. Read more in Jeff’s C7gn and Channy’s Hpc7g blog posts.

Amazon EFS – Provisioned Throughput now supports up to 10 GiB/s (from 3 GiB/s) for reads and 3 GiB/s (from 1 GiB/s) for writes.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
Architecture diagram for AWS Distro for OpenTelemetry sample app.A few more news items and blog posts you might have missed:

Good tips – Mitigate Common Web Threats with One Click in Amazon CloudFront

A nice series – Let’s Architect! Open-source technologies on AWS

An interesting solution – Deploy a serverless ML inference endpoint of large language models using FastAPI, AWS Lambda, and AWS CDK

For AWS open-source news and updates, check out the latest newsletter curated by Ricardo to bring you the most recent updates on open-source projects, posts, events, and more.

Upcoming AWS Events
Here are some opportunities to meet and learn:

AWS Applications Innovation Day (June 27) – Learn how product teams across applications, security, and artificial intelligence (AI) are collaborating with AWS Partners like Asana, Slack, Splunk, Atlassian, Okta, and more to help organizations work smarter together. For more information on the event, refer to this blog post.

AWS Summits – Get together to connect, collaborate, and learn about AWS in Hong Kong (July 20), New York (July 26), Taiwan (Aug 2 & 3), Sao Paulo (Aug 3).

AWS re:Invent (Nov 27 – Dec 1) – Join us to hear the latest from AWS, learn from experts, and connect with the global cloud community. Registration is now open.

Amazon Prime Day (July 11-12) is coming, and you can learn more in this blog post. We should keep an eye out for Jeff’s annual Prime Day post following the event.

That’s all from me for this week. Come back next Monday for another Week in Review!

— Danilo

This post is part of our Week in Review series. Check back each week for a quick roundup of interesting news and announcements from AWS!

Argonne Aurora Supercomputer Intel Max Blade Installation is Complete

Post Syndicated from Cliff Robinson original https://www.servethehome.com/argonne-aurora-supercomputer-intel-max-blade-installation-is-complete/

Today Intel and Argonne National Labs announced that the Intel Xeon Max and GPU Max Aurora supercomputer blade installation is complete

The post Argonne Aurora Supercomputer Intel Max Blade Installation is Complete appeared first on ServeTheHome.

Intel Manufacturing Gets its Own Profit and Loss Potentially Gearing Up for a Spin-Off

Post Syndicated from Patrick Kennedy original https://www.servethehome.com/intel-manufacturing-gets-its-own-profit-and-loss-potentially-gearing-up-for-a-spin-off/

Intel is giving its manufacturing arm its own P&L to help drive cost reductions. The announcement feels a lot like it is gearing for a split

The post Intel Manufacturing Gets its Own Profit and Loss Potentially Gearing Up for a Spin-Off appeared first on ServeTheHome.

New – Amazon EC2 Hpc7g Instances Powered by AWS Graviton3E Processors Optimized for High Performance Computing Workloads

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/new-amazon-ec2-hpc7g-instances-powered-by-aws-graviton3e-processors-optimized-for-high-performance-computing-workloads/

At AWS re:Invent 2022, Adam Selipsky, CEO of AWS, explained high performance computing (HPC) workloads typically can either be compute-intensive, compute- and networking-intensive, or data- and memory-intensive in his keynote.

Compute workloads include weather forecasting, computational fluid dynamics, and financial options pricing. To help with this, you have Amazon EC2 Hpc6a instances, which deliver up to 65 percent better price performance over comparable compute optimized x86-based instances.

Other HPC workloads require modeling the performance of complex structures—things like wind turbines, concrete buildings, and industrial equipment. Without enough data and memory, these models can take days or weeks to run in a cost-effective way. The Amazon EC2 Hpc6id instance is designed to deliver leading price performance for data and memory-intensive HPC workloads with higher memory bandwidth per core, faster local solid-state drive (SSD) storage, and enhanced networking with Elastic Fabric Adapter (EFA).

Announcing Amazon EC2 Hpc7g Instances
Compute-intensive HPC workloads such as weather forecasting, computational fluid dynamics, and financial options pricing also require more network performance, even better price performance, and greater energy efficiency.

Today we are announcing the general availability of Amazon EC2 Hpc7g instances, a new purpose-built instance type for tightly coupled compute and network-intensive HPC workloads.

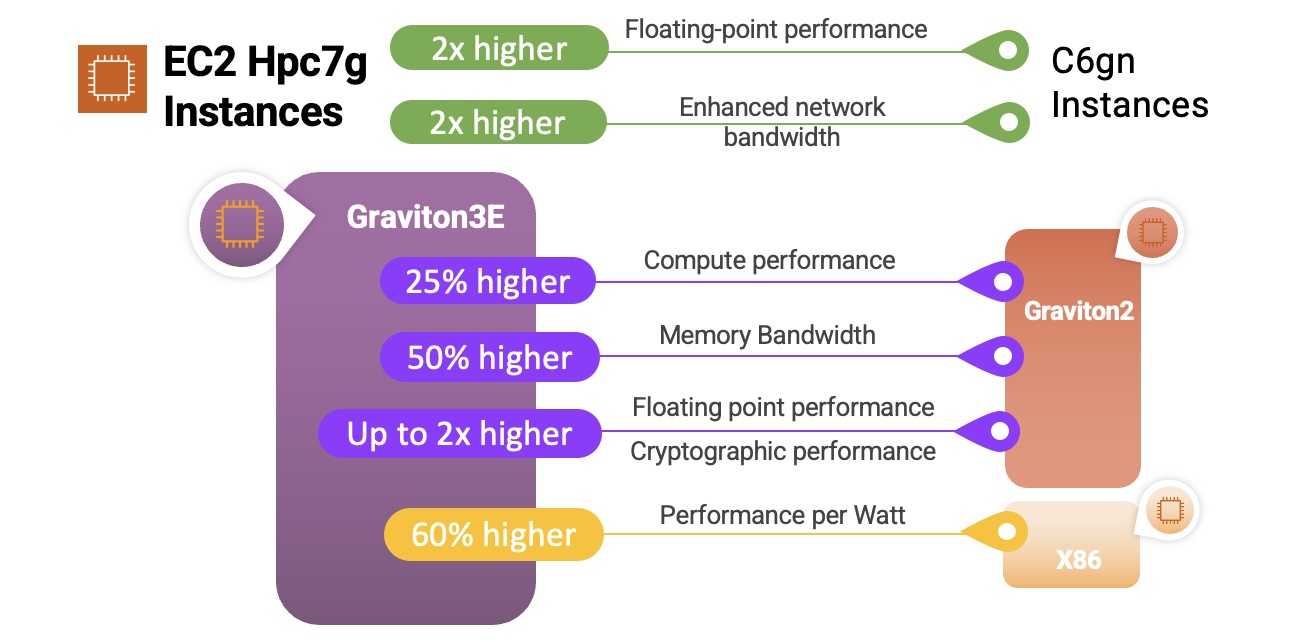
Hpc7g instances are powered by AWS Graviton3E processors that provide up to two times better floating-point performance and 200 Gbps dedicated EFA bandwidth than EC2 C6gn instances powered by AWS Graviton2 processors and are up to 60 percent more energy efficient than comparable x86 instances.

Here’s a quick infographic that shows you how the Hpc7g instances and the Graviton3E processors compare to previous instances and processors:

Hpc7g instances feature sizes of up to 64 cores of the latest AWS custom Graviton3E CPUs with 128 GiB RAM. Here are the detailed specs:

Instance Name
CPUs RAM (GiB)
EFA Network Bandwidth (Gbps) Attached Storage
hpc7g.4xlarge 16 128 Up to 200 EBS Only
hpc7g.8xlarge 32 128 Up to 200 EBS Only
hpc7g.16xlarge 64 128 Up to 200 EBS Only

Hpc7g instances are the most cost-efficient option to scale your HPC clusters on AWS. If you are considering migrating your largest HPC workloads requiring tens of thousands of cores at scale to AWS, you can take advantage of up to 200 Gbps EFA bandwidth to reduce the latency and run message passing interface (MPI) applications on parallel computing architectures while ensuring minimized power consumption on Hpc7g instances.

You can choose to use smaller sizes of Hpc7g instances to pick a lower number of cores and evenly distribute memory and network resources across the remaining cores to increase per-core performance to help reduce software licensing costs.

You can also use Hpc7g instances with AWS ParallelCluster to offer a complete HPC run-time environment that spans both x86 and arm64 instance types, giving you the flexibility to run different workload types within the same HPC cluster. You can compare and contrast performance, thus making it easier to find out what’s best for you and enabling easier porting of your workload.

Customer Story
The Water Institute is an independent, non-profit applied research organization that works across disciplines to advance science and develop integrated methods used to solve complex environmental and societal challenges.

They benchmarked the Hpc7g instances with 200 Gbps EFA using the Advanced Circulation (ADCIRC) model. ADCIRC is deployed throughout many US government agencies to simulate the movement of water due to astronomic tides, riverine flows, and atmospheric forces, including hurricanes and it is often used for real-time forecasting applications and design studies.

The model run for this application is targeted at Southern Louisiana and is the basis for most of the analysis conducted there including levee design, planning studies, and real-time hurricane storm surge forecasting applications. The left graphic above shows the full extent of the domain, while to the right of that, the high-resolution area targeted at Southern Louisiana shows flooding around the levees in New Orleans during a simulation of Hurricane Katrina.

The model contains 1.6 million vertices and 3 million elements. It’s these parameters that affect the computational complexity of the simulations. The simulations depict 18 days of astronomic tide, river inflows, and atmospheric wind and pressure forcing.

The Water Institute benchmarked against many of the instance types that would be useful for their workload types at AWS, including c6gn.16xlarge, hpc7g.16xlarge, hpc6a.48xlarge, and hpc6id.36xlarge.

The Hpc7g instance shows more than 40 percent better performance than the C6gn instance and has comparable performance to other high performance x86 instance types but with a better price-to-performance ratio. With Hpc7g instances, the Water Institute can lower its costs while maintaining the performance levels they expect.

RIKEN, who has built the powerful supercomputer, FUGAKU using arm64, is collaborating with AWS to create a virtual Fugaku using Hpc7g with Graviton3E to support Japanese manufacturers’ increasing demand for compute power. RIKEN has already confirmed that multiple Fugaku applications provide excellent performance on the AWS Graviton3E processor in the AWS cloud environment.

Also, Siemens has optimized the scalability of Simcenter STAR-CCM+ across a broad range of CPU and GPU instances on AWS. This technology is supported on Linux and available through Arm-based EC2 instances or the Fugaku supercomputer.

To hear more voices of customers and partners such as Ansys, Arup, CERFACS, ESI, Jij, ParTec, Rescale, and TotalCAE, see the Hpc7g instances page.

Now Available
Amazon EC2 Hpc7g instances are now generally available in the US East (N. Virginia) Region for purchase in On-Demand, Reserved Instance, and Savings Plan form.

To learn more, see the Amazon EC2 Hpc7g instances page. Give it a try, and please send feedback to AWS re:Post for High Performance Compute or through your usual AWS support contacts.

– Channy

New Amazon EC2 C7gn Instances: Graviton3E Processors and Up To 200 Gbps Network Bandwidth

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/new-amazon-ec2-c7gn-instances-graviton3e-processors-and-up-to-200-gbps-network-bandwidth/

The C7gn instances that we previewed last year are now available and you can start using them today. The instances are designed for your most demanding network-intensive workloads (firewalls, virtual routers, load balancers, and so forth), data analytics, and tightly-coupled cluster computing jobs. They are powered by AWS Graviton3E processors and support up to 200 Gbps of network bandwidth.

Here are the specs:

Instance Name vCPUs
Memory
Network Bandwidth
EBS Bandwidth
c7gn.medium 1 2 GiB up to 25 Gbps up to 10 Gbps
c7gn.large 2 4 GiB up to 30 Gbps up to 10 Gbps
c7gn.xlarge 4 8 GiB up to 40 Gbps up to 10 Gbps
c7gn.2xlarge 8 16 GiB up to 50 Gbps up to 10 Gbps
c7gn.4xlarge 16 32 GiB 50 Gbps up to 10 Gbps
c7gn.8xlarge 32 64 GiB 100 Gbps up to 20 Gbps
c7gn.12xlarge 48 96 GiB 150 Gbps up to 30 Gbps
c7gn.16xlarge 64 128 GiB 200 Gbps up to 40 Gbps

The increased network bandwidth is made possible by the new 5th generation AWS Nitro Card. As another benefit, these instances deliver the lowest Elastic Fabric Adapter (EFA) latency of any current EC2 instance.

Here’s a quick infographic that shows you how the C7gn instances and the Graviton3E processors compare to previous instances and processors:

As you can see, the Graviton3E processors deliver substantially higher memory bandwidth and compute performance than the Graviton2 processors, along with higher vector instruction performance than the Graviton3 processors.

C7gn instances are available in the US East (Ohio, N. Virginia), US West (Oregon), and Europe (Ireland) AWS Regions in On-Demand, Reserved Instance, Spot, and Savings Plan form. Dedicated Instances and Dedicated Hosts are also available.

— Jeff;

Learn how to streamline and secure your SaaS applications at AWS Applications Innovation Day

Post Syndicated from Phil Goldstein original https://aws.amazon.com/blogs/aws/learn-how-to-streamline-and-secure-your-saas-applications-at-aws-applications-innovation-day/

Companies continue to adopt software as a service (SaaS) applications at a rapid clip, with recent research showing that the average SaaS portfolio now has at least 200 applications. While organizations purchase these purpose-built tools to make their employees more productive, they now must contend with growing security complexities, context switching, and data silos.

If your company faces these issues, or you want to avoid them in the future, join us on Tuesday, June 27, for a free-to-attend online event AWS Applications Innovation Day. AWS will stream the event simultaneously across multiple platforms, including LinkedIn Live, Twitter, YouTube, and Twitch. You can also join us in person in Seattle to hear from Dilip Kumar, Vice President of AWS Applications and an executive panel with AWS Partners Splunk, Asana, and Okta.

Join us for Applications Innovation Day June 27, 2023.

Applications Innovation Day is designed to give you the tools you need to improve how your organization uses and secures SaaS applications. Sessions throughout the day will show you how you can secure data while providing your employees with the best tools for the job. You’ll also learn how to support the right mix of applications to improve workforce collaboration, and how to use generative artificial intelligence securely and effectively to improve insights and enhance employee productivity.

We’ll start the virtual broadcast with a keynote from Dilip Kumar, Vice President of AWS Applications, who will discuss the way we use and govern SaaS applications at AWS. He’ll also discuss how we’ll make it easier to deploy purpose-built SaaS applications like Asana, Okta, Splunk, Zoom, and others across your business, including the announcement of some exciting new innovations from AWS.

AWS product leaders will present technical breakout sessions during the day on the productivity and security aspects of managing a SaaS application tech stack. Sessions will cover a wide range of topics, including how the nature of productivity at work is changing, how AI is transforming SaaS applications and collaboration, how you can improve your security observability across your applications, and how you can create custom analytics on SaaS application activity.

Overall, the event is a great opportunity for security leaders, IT administrators and operations leaders, and anyone leading digital workplace and transformation initiatives to learn how to better leverage and govern SaaS applications.

To register for AWS Applications Innovation Day, simply go to the event page.

AWS Week in Review – Amazon EC2 Instance Connect Endpoint, Detective, Amazon S3 Dual Layer Encryption, Amazon Verified Permission – June 19, 2023

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-week-in-review-amazon-ec2-instance-connect-endpoint-detective-amazon-s3-dual-layer-encryption-amazon-verified-permission-june-19-2023/

This week, I’ll meet you at AWS partner’s Jamf Nation Live in Amsterdam where we’re showing how to use Amazon EC2 Mac to deploy your remote developer workstations or configure your iOS CI/CD pipelines in the cloud.Mac in an instant

Last Week’s Launches
While I was traveling last week, I kept an eye on the AWS News. Here are some launches that got my attention.

Amazon EC2 Instance Connect Endpoint. Endpoint for EC2 Instance Connect allows you to securely access Amazon EC2 instances using their private IP addresses, making the use of bastion hosts obsolete. Endpoint for EC2 Instance Connect is by far my favorite launch from last week. With EC2 Instance Connect, you use AWS Identity and Access Management (IAM) policies and principals to control SSH access to your instances. This removes the need to share and manage SSH keys. We also updated the AWS Command Line Interface (AWS CLI) to allow you to easily connect or open a secured tunnel to an instance using only its instance ID. I read and contributed to a couple of threads on social media where you pointed out that AWS Systems Manager Session Manager already offered similar capabilities. You’re right. But the extra advantage of EC2 Instance Connect Endpoint is that it allows you to use your existing SSH-based tools and libraries, such as the scp command.

Amazon Inspector now supports code scanning of AWS Lambda functions. This expands the existing capability to scan Lambda functions and associated layers for software vulnerabilities in application package dependencies. Amazon Detective also extends finding groups to Amazon Inspector. Detective automatically collects findings from Amazon Inspector, GuardDuty, and other AWS security services, such as AWS Security Hub, to help increase situational awareness of related security events.

Amazon Verified Permissions is generally available. If you’re designing or developing business applications that need to enforce user-based permissions, you have a new option to centrally manage application permissions. Verified Permissions is a fine-grained permissions management and authorization service for your applications that can be used at any scale. Verified Permissions centralizes permissions in a policy store and helps developers use those permissions to authorize user actions within their applications. Similarly to the way an identity provider simplifies authentication, a policy store lets you manage authorization in a consistent and scalable way. Read Danilo’s post to discover the details.

Amazon S3 Dual-Layer Server-Side Encryption with keys stored in AWS Key Management Service (DSSE-KMS). Some heavily regulated industries require double encryption to store some type of data at rest. Amazon Simple Storage Service (Amazon S3) offers DSSE-KMS, a new free encryption option that provides two layers of data encryption, using different keys and different implementation of the 256-bit Advanced Encryption Standard with Galois Counter Mode (AES-GCM) algorithm. My colleague Irshad’s post has all the details.

AWS CloudTrail Lake Dashboards provide out-of-the-box visibility and top insights from your audit and security data directly within the CloudTrail Lake console. CloudTrail Lake features a number of AWS curated dashboards so you can get started right away – with no required detailed dashboard setup or SQL experience.

AWS IAM Identity Center now supports automated user provisioning from Google Workspace. You can now connect your Google Workspace to AWS IAM Identity Center (successor to AWS Single Sign-On) once and manage access to AWS accounts and applications centrally in IAM Identity Center.

AWS CloudShell is now available in 12 additional regions. AWS CloudShell is a browser-based shell that makes it easier to securely manage, explore, and interact with your AWS resources. The list of the 12 new Regions is detailed in the launch announcement.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
Here are some other updates and news that you might have missed:

  • AWS Extension for Stable Diffusion WebUI. WebUI is a popular open-source web interface that allows you to easily interact with Stable Diffusion generative AI. We built this extension to help you to migrate existing workloads (such as inference, train, and ckpt merge) from your local or standalone servers to the AWS Cloud.
  • GoDaddy developed a multi-Region, event-driven system. Their system handles 400 millions events per day. They plan to scale it to process 2 billion messages per day in a near future. My colleague Marcia explains the detail of their architecture in her post.
  • The Official AWS Podcast – Listen each week for updates on the latest AWS news and deep dives into exciting use cases. There are also official AWS podcasts in several languages. Check out the podcasts in French, German, Italian, and Spanish.
  • AWS Open Source News and Updates – This is a newsletter curated by my colleague Ricardo to bring you the latest open source projects, posts, events, and more.

Upcoming AWS Events
Check your calendars and sign up for these AWS events:

  • AWS Silicon Innovation Day (June 21) – A one-day virtual event that will allow you to better understand AWS Silicon and how you can use the Amazon EC2 chip offerings to your benefit. My colleague Irshad shared the details in this post. Register today.
  • AWS Global Summits – There are many AWS Summits going on right now around the world: Milano (June 22), Hong Kong (July 20), New York (July 26), Taiwan (Aug 2 & 3), and Sao Paulo (Aug 3).
  • AWS Community Day – Join a community-led conference run by AWS user group leaders in your region: Manila (June 29–30), Chile (July 1), and Munich (September 14).
  • AWS User Group Perú Conf 2023 (September 2023). Some of the AWS News blog writer team will be present: Marcia, Jeff, myself, and our colleague Startup Developer Advocate Mark. Save the date and register today.
  • CDK Day – CDK Day is happening again this year on September 29. The call for papers for this event is open, and this year we’re also accepting talks in Spanish. Submit your talk here.

That’s all for this week. Check back next Monday for another Week in Review!

This post is part of our Week in Review series. Check back each week for a quick roundup of interesting news and announcements from AWS!
— seb

How GoDaddy Implemented a Multi-Region Event-Driven Platform at Scale

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/aws/how-godaddy-implemented-a-multi-region-event-driven-platform-at-scale/

GoDaddy, a leading global provider of domain registration and web hosting services, has served over 84 million domains and 22 million customers since its establishment in 1997. Among its various internal systems, the Customer Signal Platform provides tooling to capture, analyze, and act on customer and product data to drive better business outcomes. With this platform, GoDaddy can track user visits and interactions on its website and use meaningful event data to improve its customer experience and overall business performance.

Nowadays, the Customer Signal Platform processes 400 million events every day. As GoDaddy expands its integrations, it aims to increase this number to 2 billion events per day in the near future.

When building the Customer Signal Platform, GoDaddy had three main requirements for the system architecture:

  1. Minimize their operational load.
  2. Scale automatically as traffic changes.
  3. Provide high availability and ensure that all the customer signals are captured.

Amazon EventBridge Event Bus
After evaluating many options against their requirements, GoDaddy decided to implement the customer signal platform using Amazon EventBridge Event Bus. EventBridge Event Bus is a serverless event bus that helps you receive, filter, transform, route, and deliver events. Because EventBridge is serverless, it requires minimal configuration to get started and scales automatically—GoDaddy’s first two requirements were checked.

To comply with the third requirement, the solution needed to provide business continuity and ensure that no event is lost from the moment the client produces it until it gets to the platform to be analyzed. EventBridge Event Bus comes with many features that helped GoDaddy build their application with this requirement in mind.

The main feature that GoDaddy took advantage of was global endpoints. EventBridge global endpoints provide a reliable and simple way to improve the business continuity of event-driven applications. This new feature, added in 2022, allows customers to build a multi-Region event-driven application.

EventBridge Global Endpoints
Global endpoints allow you to configure a managed DNS endpoint in EventBridge, to which your applications will send events. Then you need to configure two custom event buses in two distinct AWS Regions. One is the primary Region, and the other is the failover, or secondary Region. The failover of events is decided based on the health indicated by an Amazon Route 53 health check. When the health check is healthy, the events are routed from the global endpoint to the custom event bus in the primary Region. And if the health check is unhealthy, then the global endpoint will send the events to the event bus in the secondary Region.

Healthcheck status

The simplest configuration for global endpoints is the active/archive configuration. This configuration provides business continuity and simplicity at the same time. The active/archive configuration defines two different Regions. The primary Region is where the application is deployed and all the business processes are happening. The archive Region is where only a custom bus is deployed and all the events are archived.

In addition, there is a bidirectional replication rule between the buses in separate Regions. In the normal case, when there are no errors, whenever an event arrives at the custom bus in the primary Region, the event is automatically replicated to the archive custom bus in the secondary Region.

In the case of failover, the global endpoint redirects the events to the secondary Region, where they get archived for processing at another time.

Active/ Archive configuration

GoDaddy Implementation of Global Endpoints
GoDaddy was looking for a solution that minimized their operations load while still providing business continuity, and that is why they adopted global endpoints and the active/archive configuration. In this way, they could have the event processing logic in their primary Region and have a secondary Region in case of any issues.

In their configuration, events are archived in the secondary Region for 30 days, after which the events expire. In the case of a failover, because they don’t need to process the events in real time, they collect them in the archive. If the issue is resolved within 24 hours, the retention period for the replication rule, the events are sent automatically to the primary Region. If the issue is solved in more than 24 hours the events need to be replayed to the primary Region.

The following image shows what their current solution looks like. They are working with two Regions. US West (Oregon) is their primary Region and is the location of the data lake, which is the primary consumer of the events. US East (N. Virginia) is the secondary Region. Events are being produced in different clients; from the clients, they are sent to Amazon API Gateway. GoDaddy deployed two API Gateways in their two Regions. The events are sent to the API Gateway with the smallest latency from the client. To do that, they use latency-based routing provided by Amazon Route 53. Then events are sent to an AWS Lambda function that validates the events and forwards them to the EventBridge global endpoint at the DNS level.

GoDaddy architecture

The global endpoint is configured with the active/archive setup, and the failover is configured to be triggered via a Route 53 health check that monitors an Amazon CloudWatch alarm. That alarm observes the IngestionToInvocationStartLatency metric in the primary Region.

IngestionToInvocationStartLatency is a service-level metric that exposes the time to process events from the point at which they are ingested by EventBridge to the point the first invocation of a target in the configured rules is made. This metric is measured across all the rules in your bus and provides an indication of the health of the EventBridge service. Any extended periods of high latency over 30 seconds indicate a service disruption.

When the system is in the normal state, the events are forwarded from the global endpoint to the custom ingress event bus in the primary Region. That custom event bus has replication enabled; this means that all the events that arrive at the bus get replicated automatically in the secondary Region custom ingress event bus.

All the events received by the ingress event bus are sent to the enrichment function. This function performs basic validation and authentication, and it enriches the event data to make sure that all the events from different clients are standard.

From there, the events are forwarded to the data platform event bus to be sent to the different consumer targets. The main target is their data lake solution, which analyzes all the events.

What Was the Impact?
For GoDaddy, business continuity is important, and their customer signals are not getting lost due to any issue with their platform. This makes them confident that they can expand their customer signal platforms from 400 million events per day to 2 billion events per day without introducing any additional operations overhead.

Now, they can confidently process hundreds of millions of events per day to their system, and they can keep on growing. The following image shows the number of events ingested by global endpoints in a normal day.

Events ingested

While GoDaddy’s use of the active/archive pattern enables them to ensure they never lose any events, they’re already starting to see certain use cases where they want to minimize any delays in processing their events, even when service disruptions occur. Because they’re already replicating their events to a secondary Region, they can deploy their most critical consumers to both Regions and enable an active/active configuration for their mission-critical systems. Active/active configuration allows you to process parallel events in both the primary and secondary Regions, simplifying the processing of events even during disruptions and enabling business continuity.

The vision when building the Customer Signal Platform was to align with GoDaddy’s high bar for reliability, scalability, and maintainability and, at the same time, keep the platform self-service so that developers can focus on business needs. This led GoDaddy to choose Amazon EventBridge global endpoints and serverless technologies to build this solution.

GoDaddy Customer Signal Platform is an excellent example of what serverless technologies enable. By leveraging the cloud to handle as much of the undifferentiated heavy lifting as possible, GoDaddy has reduced the operational complexity of setting up an event bus for a multi-Region strategy, implemented failover mechanisms in the case of Regional distruptions, and ensured that events are not lost by enabling replication. Global endpoints active/archive configuration improves the availability of customer applications with the least amount of configuration changes.

If you want to get started with EventBridge global endpoints, you can check out this talk on event-driven applications. For a working demo on how to use EventBridge global endpoints for failover events, check out this Serverless Land repository.

— Marcia

Discover How AWS Designed Silicon Fuels Customer Outcomes at AWS Silicon Innovation Day

Post Syndicated from Irshad Buchh original https://aws.amazon.com/blogs/aws/discover-how-aws-designed-silicon-fuels-customer-outcomes-at-aws-silicon-innovation-day/

We hope you will join us on Wednesday, June 21, for a free-to-attend online event, AWS Silicon Innovation Day. AWS will stream the event simultaneously across multiple platforms, including LinkedIn Live, Twitter, YouTube, and Twitch.

AWS Silicon Innovation Day is a one-day virtual event on June 21, 2023, that will allow you to better understand AWS Silicon and how you can use AWS’s unique Amazon EC2 chip offerings to your benefit. AWS has designed and developed purpose-built silicon specifically for the cloud.

During this event, you will have the opportunity to hear directly from senior leaders at AWS. Our panel of lead architects, engineers, customers, and analysts will provide insights into our silicon journey. Through deep dives into our cutting-edge silicon design and customer success stories, the panel will provide insights on security enhancements and cost-saving opportunities. Here are some of the highlights you can expect from this event.

Leadership session – To kick off the day, we have a Leadership session featuring Dave Brown, VP of Amazon EC2 and Dr. Ruba Borno, VP of WW Channels and Alliances joining us on stage. Dave will engage in a discussion with Ruba about how you can benefit from the innovation AWS delivers with its silicon technology.

AI/ML session – Gary Szilagyi, VP of Annapurna Labs will discuss with Nafea Bshara, co-founder of Annapurna Labs the utilization of chipset development by his team to create specialized chips for Generative AI, CPU, and the AWS Nitro system. He will highlight how you can harness the Annapurna mindset to develop not only CPUs but also tailor-made chips with specific purposes in mind.

Customer session – Jeff Barr, VP of AWS Evangelism, and Tiffany Wissner, Director of Product Marketing, will delve into insights from our customers. They will share anecdotes and experiences gathered from various sources, such as re:Invent, summits, and developer events, where you have expressed how you harnessed AWS silicon to drive your own remarkable innovations.

Networking session – JR Rivers, Senior Principal Engineer, and Madhura Kale, Senior Product Manager will shed light on the impact of silicon innovation, not only on the benefits you experience using our CPUs, GPUs, or Nitro System, but also on the transformation of AWS’s network infrastructure. They will delve into the realm of networking advancements, showcasing some of the latest innovations and highlighting the instrumental role played by AWS silicon in powering these developments.

Arm and Nitro Innovation session – Anthony Liguori, VP and Fellow, Nitro System architecture will be joined by Ali Saidi, Director of Annapurna Labs to discuss harnessing the power of hardware and software in tandem to drive the development of cutting-edge silicon technologies.

Analyst and Executive session – Raj Pai, VP of Amazon EC2 Product Management will engage in a conversation with an analyst, delving into the realm of silicon innovation in the cloud.

Join us for Silicon Innovation Day Wednesday June 21 9:00am - 4:00pm PDT

No advance registration is needed to participate in AWS Silicon Innovation Day, but you can add an event reminder to your calendar by registering on the event page. We sincerely hope that you will join us in embracing the excitement and seizing the valuable learning opportunities at this new event!

Meet you there.

— Irshad

New – Amazon S3 Dual-Layer Server-Side Encryption with Keys Stored in AWS Key Management Service (DSSE-KMS)

Post Syndicated from Irshad Buchh original https://aws.amazon.com/blogs/aws/new-amazon-s3-dual-layer-server-side-encryption-with-keys-stored-in-aws-key-management-service-dsse-kms/

Today, we are launching Amazon S3 dual-layer server-side encryption with keys stored in AWS Key Management Service (DSSE-KMS), a new encryption option in Amazon S3 that applies two layers of encryption to objects when they are uploaded to an Amazon Simple Storage Service (Amazon S3) bucket. DSSE-KMS is designed to meet National Security Agency CNSSP 15 for FIPS compliance and Data-at-Rest Capability Package (DAR CP) Version 5.0 guidance for two layers of CNSA encryption. Using DSSE-KMS, you can fulfill regulatory requirements to apply multiple layers of encryption to your data.

Amazon S3 is the only cloud object storage service where customers can apply two layers of encryption at the object level and control the data keys used for both layers. DSSE-KMS makes it easier for highly regulated customers to fulfill rigorous security standards, such as US Department of Defense (DoD) customers.

With DSSE-KMS, you can specify dual-layer server-side encryption (DSSE) in the PUT or COPY request for an object or configure your S3 bucket to apply DSSE to all new objects by default. You can also enforce DSSE-KMS using IAM and bucket policies. Each layer of encryption uses a separate cryptographic implementation library with individual data encryption keys. DSSE-KMS helps protect sensitive data against the low probability of a vulnerability in a single layer of cryptographic implementation.

DSSE-KMS simplifies the process of applying two layers of encryption to your data, without having to invest in infrastructure required for client-side encryption. Each layer of encryption uses a different implementation of the 256-bit Advanced Encryption Standard with Galois Counter Mode (AES-GCM) algorithm. DSSE-KMS uses the AWS Key Management Service (AWS KMS) to generate data keys, allowing you to control your customer managed keys by setting permissions per key and specifying key rotation schedules. With DSSE-KMS, you can now query and analyze your dual-encrypted data with AWS services such as Amazon Athena, Amazon SageMaker, and more.

With this launch, Amazon S3 now offers four options for server-side encryption:

  1. Server-side encryption with Amazon S3 managed keys (SSE-S3)
  2. Server-side encryption with AWS KMS (SSE-KMS)
  3. Server-side encryption with customer-provided encryption keys (SSE-C)
  4. Dual-layer server-side encryption with keys stored in KMS (DSSE-KMS)

Let’s see how DSSE-KMS works in practice.

Create an S3 Bucket and Turn on DSSE-KMS
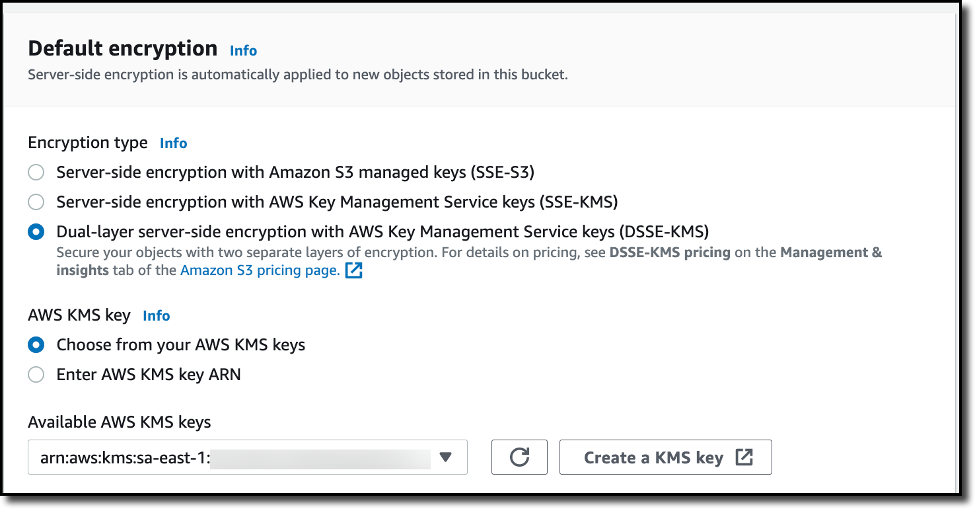
To create a new bucket in the Amazon S3 console, I choose Buckets in the navigation pane. I choose Create bucket, and I select a unique and meaningful name for the bucket. Under Default encryption section, I choose DSSE-KMS as the encryption option. From the available AWS KMS keys, I select a key for my requirements. Finally, I choose Create bucket to complete the creation of the S3 bucket, encrypted by DSSE-KMS encryption settings.

Encryption

Upload an Object to the DSSE-SSE enabled S3 Bucket
In the Buckets list, I choose the name of the bucket that I want to upload an object to. On the Objects tab for the bucket, I choose Upload. Under Files and folders, I choose Add files. I then choose a file to upload, and then choose Open. Under Server-side encryption, I choose Do not specify an encryption key. I then choose Upload.

Server Side Encryption

Once the object is uploaded to the S3 bucket, I notice that the uploaded object inherits the Server-side encryption settings from the bucket.

Server Side Encryption Setting

Download a DSSE-KMS Encrypted Object from an S3 Bucket
I select the object that I previously uploaded and choose Download or choose Download as from the Object actions menu. Once the object is downloaded, I open it locally, and the object is decrypted automatically, requiring no change to client applications.

Now Available
Amazon S3 dual-layer server-side encryption with keys stored in AWS KMS (DSSE-KMS) is available today in all AWS Regions. You can get started with DSSE-KMS via the AWS CLI or AWS Management Console. To learn more about all available encryption options on Amazon S3, visit the Amazon S3 User Guide. For pricing information on DSSE-KMS, visit the Amazon S3 pricing page (Storage tab) and the AWS KMS pricing page.

— Irshad

Simplify How You Manage Authorization in Your Applications with Amazon Verified Permissions – Now Generally Available

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/simplify-how-you-manage-authorization-in-your-applications-with-amazon-verified-permissions-now-generally-available/

When developing a new application or integrating an existing one into a new environment, user authentication and authorization require significant effort to be correctly implemented. In the past, you would have built your own authentication system, but today you can use an external identity provider like Amazon Cognito. Yet, authorization logic is typically implemented in code.

This might begin simply enough, with all users assigned a role for their job function. However, over time, these permissions grow increasingly complex. The number of roles expands, as permissions become more fine-grained. New use cases drive the need for custom permissions. For instance, one user might share a document with another in a different role, or a support agent might require temporary access to a customer account to resolve an issue. Managing permissions in code is prone to errors, and presents significant challenges when auditing permissions and deciding who has access to what, particularly when these permissions are expressed in different applications and using multiple programming languages.

At re:Invent 2022, we introduced in preview Amazon Verified Permissions, a fine-grained permissions management and authorization service for your applications that can be used at any scale. Amazon Verified Permissions centralizes permissions in a policy store and helps developers use those permissions to authorize user actions within their applications. Similar to how an identity provider simplifies authentication, a policy store let you manage authorization in a consistent and scalable way.

To define fine-grained permissions, Amazon Verified Permissions uses Cedar, an open-source policy language and software development kit (SDK) for access control. You can define a schema for your authorization model in terms of principal types, resource types, and valid actions. In this way, when a policy is created, it is validated against your authorization model. You can simplify the creation of similar policies using templates. Changes to the policy store are audited so that you can see of who made the changes and when.

You can then connect your applications to Amazon Verified Permissions through AWS SDKs to authorize access requests. For each authorization request, the relevant policies are retrieved and evaluated to determine whether the action is permitted or not. You can reproduce those authorization requests to confirm that permissions work as intended.

Today, I am happy to share that Amazon Verified Permissions is generally available with new capabilities and a simplified user experience in the AWS Management Console.

Let’s see how you can use it in practice.

Creating a Policy Store with Amazon Verified Permissions
In the Amazon Verified Permissions console, I choose Create policy store. A policy store is a logical container that stores policies and schema. Authorization decisions are made based on all the policies present in a policy store.

To configure the new policy store, I can use different methods. I can start with a guided setup, a sample policy store (such as for a photo-sharing app, an online store, or a task manager), or an empty policy store (recommended for advanced users). I select Guided setup, enter a namespace for my schema (MyApp), and choose Next.

Console screenshot.

Resources are the objects that principals can act on. In my application, I have Users (principals) that can create, read, update, and delete Documents (resources). I start to define the Documents resource type.

I enter the name of the resource type and add two required attributes:

  • owner (String) to specify who is the owner of the document.
  • isPublic (Boolean) to flag public documents that anyone can read.

Console screenshot.

I specify four actions for the Document resource type:

  • DocumentCreate
  • DocumentRead
  • DocumentUpdate
  • DocumentDelete

Console screenshot.

I enter User as the name of the principal type that will be using these actions on Documents. Then, I choose Next.

Console screenshot.

Now, I configure the User principal type. I can use a custom configuration to integrate an external identity source, but in this case, I use an Amazon Cognito user pool that I created before. I choose Connect user pool.

Console screenshot.

In the dialog, I select the AWS Region where the user pool is located, enter the user pool ID, and choose Connect.

Console screenshot.

Now that the Amazon Cognito user pool is connected, I can add another level of protection by validating the client application IDs. For now, I choose not to use this option.

In the Principal attributes section, I select which attributes I am planning to use for attribute-based access control in my policies. I select sub (the subject), used to identify the end user according to the OpenID Connect specification. I can select more attributes. For example, I can use email_verified in a policy to give permissions only to Amazon Cognito users whose email has been verified.

Console screenshot.

As part of the policy store creation, I create a first policy to give read access to user danilop to the doc.txt document.

Console screenshot.

In the following code, the console gives me a preview of the resulting policy using the Cedar language.

permit(
  principal == MyApp::User::"danilop",
  action in [MyApp::Action::"DocumentRead"],
  resource == MyApp::Document::"doc.txt"
) when {
  true
};

Finally, I choose Create policy store.

Adding Permissions to the Policy Store
Now that the policy store has been created, I choose Policies in the navigation pane. In the Create policy dropdown, I choose Create static policy. A static policy contains all the information needed for its evaluation. In my second policy, I allow any user to read public documents. By default everything is forbidden, so in Policy Effect I choose Permit.

In the Policy scope, I leave All principals and All resources selected, and select the DocumentRead action. In the Policy section, I change the when condition clause to limit permissions to resources where isPublic is equal to true:

permit (
  principal,
  action in [MyApp::Action::"DocumentRead"],
  resource
)
when { resource.isPublic };

I enter a description for the policy and choose Create policy.

For my third policy, I create another static policy to allow full access to the owner of a document. Again, in Policy Effect, I choose Permit and, in the Policy scope, I leave All principals and All resources selected. This time, I also leave All actions selected.

In the Policy section, I change the when condition clause to limit permissions to resources where the owner is equal to the sub of the principal:

permit (principal, action, resource)
when { resource.owner == principal.sub };

In my application, I need to allow read access to specific users that are not owners of a document. To simplify that, I create a policy template. Policy templates let me create policies from a template that uses placeholders for some of their values, such as the principal or the resource. The placeholders in a template are keywords that start with the ? character.

In the navigation pane, I choose Policy templates and then Create policy template. I enter a description and use the following policy template body. When using this template, I can specify the value for the ?principal and ?resource placeholders.

permit(
  principal == ?principal,
  action in [MyApp::Action::"DocumentRead"],
  resource == ?resource
);

I complete the creation of the policy template. Now, I use the template to simplify the creation of policies. I choose Policies in the navigation pane, and then Create a template-linked policy in the Create policy dropdown. I select the policy template I just created and choose Next.

To give access to a user (danilop) for a specific document (new-doc.txt), I just pass the following values (note that MyApp is the namespace of the policy store):

  • For the Principal: MyApp::User::"danilop"
  • For the Resource: MyApp::Document::"new-doc.txt"

I complete the creation of the policy. It’s now time to test if the policies work as expected.

Testing Policies in the Console
In my applications, I can use the AWS SDKs to run an authorization request. The console provides a way to to simulate what my applications would do. I choose Test bench in the navigation pane. To simplify testing, I use the Visual mode. As an alternative, I have the option to use the same JSON syntax as in the SDKs.

As Principal, I pass the janedoe user. As Resource, I use requirements.txt. It’s not a public document (isPublic is false) and the owner attribute is equal to janedoe‘s sub. For the Action, I select MyApp::Action::"DocumentUpdate".

When running an authorization request, I can pass Additional entities with more information about principals and resources associated with the request. For now, I leave this part empty.

I choose Run authorization request at the top to see the decision based on the current policies. As expected, the decision is allow. Here, I also see which policies hav been satisfied by the authorization request. In this case, it is the policy that allows full access to the owner of the document.

I can test other values. If I change the owner of the document and the action to DocumentRead, the decision is deny. If I then set the resource attribute isPublic to true, the decision is allow because there is a policy that permits all users to read public documents.

Handling Groups in Permissions
The administrative users in my application need to be able to delete any document. To do so, I create a role for admin users. First, I choose Schema in the navigation pane and then Edit schema. In the list of entity types, I choose to add a new one. I use Role as Type name and add it. Then, I select User in the entity types and edit it to add Role as a parent. I save changes and create the following policy:

permit (
  principal in MyApp::Role::"admin",
  action in [MyApp::Action::"DocumentDelete"],
  resource
);

In the Test bench, I run an authorization request to check if user jeffbarr can delete (DocumentDelete) resource doc.txt. Because he’s not the owner of the resource, the request is denied.

Now, in the Additional entities, I add the MyApp::User entity with jeffbarr as identifier. As parent, I add the MyApp::Role entity with admin as identifier and confirm. The console warns me that entity MyApp::Role::"admin" is referenced, but it isn’t included in additional entities data. I choose to add it and fix this issue.

I run an authorization request again, and it is now allowed because, according to the additional entities, the principal (jeffbarr) is an admin.

Using Amazon Verified Permissions in Your Application
In my applications, I can run an authorization requests using the isAuthorized API action (or isAuthrizedWithToken, if the principal comes from an external identity source).

For example, the following Python code uses the AWS SDK for Python (Boto3) to check if a user has read access to a document. The authorization request uses the policy store I just created.

import boto3
import time

verifiedpermissions_client = boto3.client("verifiedpermissions")

POLICY_STORE_ID = "XAFTHeCQVKkZhsQxmAYXo8"

def is_authorized_to_read(user, resource):

    authorization_result = verifiedpermissions_client.is_authorized(
        policyStoreId=POLICY_STORE_ID, 
        principal={"entityType": "MyApp::User", "entityId": user}, 
        action={"actionType": "MyApp::Action", "actionId": "DocumentRead"},
        resource={"entityType": "MyApp::Document", "entityId": resource}
    )

    print('Can {} read {} ?'.format(user, resource))

    decision = authorization_result["decision"]

    if decision == "ALLOW":
        print("Request allowed")
        return True
    else:
        print("Request denied")
        return False

if is_authorized_to_read('janedoe', 'doc.txt'):
    print("Here's the doc...")

if is_authorized_to_read('danilop', 'doc.txt'):
    print("Here's the doc...")

I run this code and, as you can expect, the output is in line with the tests run before.

Can janedoe read doc.txt ?
Request denied
Can danilop read doc.txt ?
Request allowed
Here's the doc...

Availability and Pricing
Amazon Verified Permissions is available today in all commercial AWS Regions, excluding those that are based in China.

With Amazon Verified Permissions, you only pay for what you use based on the number of authorization requests and API calls made to the service.

Using Amazon Verified Permissions, you can configure fine-grained permissions using the Cedar policy language and simplify the code of your applications. In this way, permissions are maintained in a centralized store and are easier to audit. Here, you can read more about how we built Cedar with automated reasoning and differential testing.

Manage authorization for your applications with Amazon Verified Permissions.

— Danilo
Zabbix SNMP monitoring one-day training course

Post Syndicated from Arturs Lontons original https://blog.zabbix.com/zabbix-snmp-monitoring-one-day-training-course/25746/

SNMP – Simple network management protocol is a networking protocol that is extremely prevalent in network hardware such as switches and routers, as well as a variety of other devices such as printers, power supplies and even regular server hosts. Depending on the device, a wide array of metrics can be retrieved by using SNMP without the need to deploy any additional software on the target device. Our newly introduced Zabbix SNMP monitoring one-day extra course will teach you all you need to know about SNMP and how to use Zabbix to get the most out of your SNMP devices with the most optimal data collection approach.

Course contents

The goal of the course is to introduce the core concepts behind SNMP and provide the attendees with the skills necessary to extract the required metrics from SNMP endpoints. The course covers topics such as:

  • SNMP core concepts
  • SNMP command line utilities
  • Differences between SNMP versions
  • SNMP resource discovery with Zabbix Low-level discovery feature
  • Optimizing SNMP data collection with the SNMP walk[*] item introduced in Zabbix 6.4
  • Configuring and monitoring SNMP traps

The course will be hosted by a Zabbix Certified Trainer with thorough experience in SNMP monitoring and Zabbix configuration. The courses are designed with open Q&A sessions in mind, where attendees can discuss their current and potential use cases and how the course contents can be applied to their own real-life scenarios.

Zabbix Certified Specialist on-site training

SNMP monitoring in Zabbix 6.4 and newer versions

Zabbix 6.4 introduces a whole new approach to bulk SNMP monitoring – the walk[*] item. During the course, attendees will learn how the new bulk data collection approach greatly increases the metric collection speed and reduces the potential performance impact on the monitoring endpoint. The course covers the main differences between the old and new approaches and demonstrates how the new SNMP items can be configured in the correct manner. Trainers will also demonstrate and provide the opportunity to practice SNMP resource discovery with the new walk[*] item and Zabbix low-level discovery (LLD) features.

Practical tasks

Depending on the device and vendor, configuring SNMP monitoring can be both very simple or it may require understanding the underlying OID structure to find the data that you’re looking for. To guide our students through real-life scenarios in understanding how SNMP monitoring may differ across devices and vendors, the course includes practical tasks, during which the participants will get the opportunity to configure Zabbix SNMP monitoring for an array of network devices belonging to a selection of the most popular vendors, such as Cisco, HP and Mikrotik. By the end of the course, students will have both a theoretical and practical understanding of SNMP as a protocol and how it can be used by Zabbix for metric collection and problem detection.

At the end of the course, every attendee will receive the course attendance certificate.

Sign up for the SNMP monitoring Zabbix training course and check our other one-day extra courses by visiting the Zabbix Training Extra Courses page.

The post Zabbix SNMP monitoring one-day training course appeared first on Zabbix Blog.

AWS Week in Review – Automate DLQ Redrive for SQS, Lambda Supports Ruby 3.2, and More – June 12, 2023

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/aws/aws-week-in-review-automate-dlq-redrive-for-sqs-lambda-supports-ruby-3-2-and-more-june-12-2023/

Today I’m boarding a plane for Madrid. I will attend the AWS Summit Madrid this Thursday, and I will take Serverlesspresso with me. Serverlesspresso is a demo that we take to events, in where you can learn how to build event-driven architectures with serverless. If you are visiting an AWS Summit, most probably you will find one of our booths.

Serverlesspresso at Madrid

Last Week’s Launches
Here are some launches that got my attention during the previous week.

Amazon SQS – Customers were very excited when we announced the DLQ redrive for Amazon SQS as that feature helped them to easily redirect the failed messages. This week we added support for AWS SDK and CLI for this feature, allowing you to redrive the messages on the DLQ automatically, making it even easier to use this feature. You can read Seb’s blog post about this new feature to learn how to get started.

AWS Lambda – AWS Lambda now supports Ruby 3.2. Ruby 3.2 has many new improvements, for example, passing anonymous arguments to functions or having endless methods. Check out this blog post that goes in depth into each of the new features.

Amazon Fraud Detector – Amazon Fraud Detector supports event orchestration with Amazon EventBridge. This is a very important feature because now you can act on the different events that Fraud Detector emits, for example, send notifications to different stakeholders.

AWS Glue – This week, AWS Glue made two important announcements. First, it announced the general availability of AWS Glue for Ray, a new data integration engine option for AWS Glue. Ray is a popular new open-source compute framework that helps developers to scale their Python workloads. In addition, AWS Glue announced AWS Glue Data Quality, a new capability that automatically measures and monitors data lake and data pipeline quality.

Amazon Elastic Container Registry (Amazon ECR) – AWS Signer and Amazon ECR announced a new feature that allows you to sign and verify container images. You can use Signer to validate that only container images you have approved are deployed in your Amazon Elastic Kubernetes Service (Amazon EKS) clusters.

Amazon QuickSight – Amazon QuickSight now supports APIs to automate asset deployment, so you can replicate the same QuickSight assets in multiple Regions and account easily. You can read more on how to use those APIs in this blog post.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
Some other updates and news that you may have missed:

Upcoming AWS Events
Check your calendars and sign up for these AWS events:

  • AWS Silicon Innovation Day (June 21) – A one-day virtual event that focuses on AWS Silicon and how you can take advantage of AWS’s unique offerings. Learn more and register here.
  • AWS Global Summits – There are many summits going on right now around the world: Toronto (June 14), Madrid (June 15), and Milano (June 22).
  • AWS Community Day – Join a community-led conference run by AWS user group leaders in your region: Chicago (June 15), Manila (June 29–30), Chile (July 1), and Munich (September 14).
  • CDK Day – CDK Day is happening again this year on September 29. The call for papers for this event is open, and this year we are also accepting talks in Spanish. Submit your talk here.

That’s all for this week. Check back next Monday for another Week in Review!

This post is part of our Week in Review series. Check back each week for a quick roundup of interesting news and announcements from AWS!

— Marcia

New – Move Payment Processing to the Cloud with AWS Payment Cryptography

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/new-move-payment-processing-to-the-cloud-with-aws-payment-cryptography/

Cryptography is everywhere in our daily lives. If you’re reading this blog, you’re using HTTPS, an extension of HTTP that uses encryption to secure communications. On AWS, multiple services and capabilities help you manage keys and encryption, such as:

HSMs are physical devices that securely protect cryptographic operations and the keys used by these operations. HSMs can help you meet your corporate, contractual, and regulatory compliance requirements. With CloudHSM, you have access to general-purpose HSMs. When payments are involved, there are specific payment HSMs that offer capabilities such as generating and validating the personal identification number (PIN) and the security code of a credit or debit card.

Today, I am happy to share the availability of AWS Payment Cryptography, an elastic service that manages payment HSMs and keys for payment processing applications in the cloud.

Applications using payments HSMs have challenging requirements because payment processing is complex, time sensitive, and highly regulated and requires the interaction of multiple financial service providers and payment networks. Every time you make a payment, data is exchanged between two or more financial service providers and must be decrypted, transformed, and encrypted again with a unique key at each step.

This process requires highly performant cryptography capabilities and key management procedures between each payment service provider. These providers might have thousands of keys to protect, manage, rotate, and audit, making the overall process expensive and difficult to scale. To add to that, payment HSMs historically employ complex and error-prone processes, such as exchanging keys in a secure room using multiple hand-carried paper forms, each with separate key components printed on them.

Introducing AWS Payment Cryptography
AWS Payment Cryptography simplifies your implementation of cryptographic functions and key management used to secure data in payment processing in accordance with various payment card industry (PCI) standards.

With AWS Payment Cryptography, you can eliminate the need to provision and manage on-premises payment HSMs and use the provided tools to avoid error-prone key exchange processes. For example, with AWS Payment Cryptography, payment and financial service providers can begin development within minutes and plan to exchange keys electronically, eliminating manual processes.

To provide its elastic cryptographic capabilities in a compliant manner, AWS Payment Cryptography uses HSMs with PCI PTS HSM device approval. These capabilities include encryption and decryption of card data, key creation, and pin translation. AWS Payment Cryptography is also designed in accordance with PCI security standards such as PCI DSS, PCI PIN, and PCI P2PE, and it provides evidence and reporting to help meet your compliance needs.

You can import and export symmetric keys between AWS Payment Cryptography and on-premises HSMs under key encryption key (KEKs) using the ANSI X9 TR-31 protocol. You can also import and export symmetric KEKs with other systems and devices using the ANSI X9 TR-34 protocol, which allows the service to exchange symmetric keys using asymmetric techniques.

To simplify moving consumer payment processing to the cloud, existing card payment applications can use AWS Payment Cryptography through the AWS SDKs. In this way, you can use your favorite programming language, such as Java or Python, instead of vendor-specific ASCII interfaces over TCP sockets, as is common with payment HSMs.

Access can be authorized using AWS Identity and Access Management (IAM) identity-based policies, where you can specify which actions and resources are allowed or denied and under which conditions.

Monitoring is important to maintain the reliability, availability, and performance needed by payment processing. With AWS Payment Cryptography, you can use Amazon CloudWatch, AWS CloudTrail, and Amazon EventBridge to understand what is happening, report when something is wrong, and take automatic actions when appropriate.

Let’s see how this works in practice.

Using AWS Payment Cryptography
Using the AWS Command Line Interface (AWS CLI), I create a double-length 3DES key to be used as a card verification key (CVK). A CVK is a key used for generating and verifying card security codes such as CVV, CVV2, and similar values.

Note that there are two commands for the CLI (and similarly two endpoints for API and SDKs):

  • payment-cryptography for control plane operation such as listing and creating keys and aliases.
  • payment-cryptography-data for cryptographic operations that use keys, for example, to generate PIN or card validation data.

Creating a key is a control plane operation:

aws payment-cryptography create-key \
    --no-exportable \
    --key-attributes KeyAlgorithm=TDES_2KEY,
                     KeyUsage=TR31_C0_CARD_VERIFICATION_KEY,
                     KeyClass=SYMMETRIC_KEY,
                     KeyModesOfUse='{Generate=true,Verify=true}'
{
    "Key": {
        "KeyArn": "arn:aws:payment-cryptography:us-west-2:123412341234:key/42cdc4ocf45mg54h",
        "KeyAttributes": {
            "KeyUsage": "TR31_C0_CARD_VERIFICATION_KEY",
            "KeyClass": "SYMMETRIC_KEY",
            "KeyAlgorithm": "TDES_2KEY",
            "KeyModesOfUse": {
                "Encrypt": false,
                "Decrypt": false,
                "Wrap": false,
                "Unwrap": false,
                "Generate": true,
                "Sign": false,
                "Verify": true,
                "DeriveKey": false,
                "NoRestrictions": false
            }
        },
        "KeyCheckValue": "B2DD4E",
        "KeyCheckValueAlgorithm": "ANSI_X9_24",
        "Enabled": true,
        "Exportable": false,
        "KeyState": "CREATE_COMPLETE",
        "KeyOrigin": "AWS_PAYMENT_CRYPTOGRAPHY",
        "CreateTimestamp": "2023-05-26T14:25:48.240000+01:00",
        "UsageStartTimestamp": "2023-05-26T14:25:48.220000+01:00"
    }
}

To reference this key in the next steps, I can use the Amazon Resource Name (ARN) as found in the KeyARN property, or I can create an alias. An alias is a friendly name that lets me refer to a key without having to use the full ARN. I can update an alias to refer to a different key. When I need to replace a key, I can just update the alias without having to change the configuration or the code of your applications. To be recognized easily, alias names start with alias/. For example, the following command creates the alias alias/my-key for the key I just created:

aws payment-cryptography create-alias --alias-name alias/my-key \
    --key-arn arn:aws:payment-cryptography:us-west-2:123412341234:key/42cdc4ocf45mg54h
{
    "Alias": {
        "AliasName": "alias/my-key",
        "KeyArn": "arn:aws:payment-cryptography:us-west-2:123412341234:key/42cdc4ocf45mg54h"
    }
}

Before I start using the new key, I list all my keys to check their status:

aws payment-cryptography list-keys
{
    "Keys": [
        {
            "KeyArn": "arn:aws:payment-cryptography:us-west-2:123421341234:key/42cdc4ocf45mg54h",
            "KeyAttributes": {
                "KeyUsage": "TR31_C0_CARD_VERIFICATION_KEY",
                "KeyClass": "SYMMETRIC_KEY",
                "KeyAlgorithm": "TDES_2KEY",
                "KeyModesOfUse": {
                    "Encrypt": false,
                    "Decrypt": false,
                    "Wrap": false,
                    "Unwrap": false,
                    "Generate": true,
                    "Sign": false,
                    "Verify": true,
                    "DeriveKey": false,
                    "NoRestrictions": false
                }
            },
            "KeyCheckValue": "B2DD4E",
            "Enabled": true,
            "Exportable": false,
            "KeyState": "CREATE_COMPLETE"
        },
        {
            "KeyArn": "arn:aws:payment-cryptography:us-west-2:123412341234:key/ok4oliaxyxbjuibp",
            "KeyAttributes": {
                "KeyUsage": "TR31_C0_CARD_VERIFICATION_KEY",
                "KeyClass": "SYMMETRIC_KEY",
                "KeyAlgorithm": "TDES_2KEY",
                "KeyModesOfUse": {
                    "Encrypt": false,
                    "Decrypt": false,
                    "Wrap": false,
                    "Unwrap": false,
                    "Generate": true,
                    "Sign": false,
                    "Verify": true,
                    "DeriveKey": false,
                    "NoRestrictions": false
                }
            },
            "KeyCheckValue": "905848",
            "Enabled": true,
            "Exportable": false,
            "KeyState": "DELETE_PENDING"
        }
    ]
}

As you can see, there is another key I created before, which has since been deleted. When a key is deleted, it is marked for deletion (DELETE_PENDING). The actual deletion happens after a configurable period (by default, 7 days). This is a safety mechanism to prevent the accidental or malicious deletion of a key. Keys marked for deletion are not available for use but can be restored.

In a similar way, I list all my aliases to see to which keys they are they referring:

aws payment-cryptography list-aliases
{
    "Aliases": [
        {
            "AliasName": "alias/my-key",
            "KeyArn": "arn:aws:payment-cryptography:us-west-2:123412341234:key/42cdc4ocf45mg54h"
        }
    ]
}

Now, I use the key to generate a card security code with the CVV2 authentication system. You might be familiar with CVV2 numbers that are usually written on the back of a credit card. This is the way they are computed. I provide as input the primary account number of the credit card, the card expiration date, and the key from the previous step. To specify the key, I use its alias. This is a data plane operation:

aws payment-cryptography-data generate-card-validation-data \
    --key-identifier alias/my-key \
    --primary-account-number=171234567890123 \
    --generation-attributes CardVerificationValue2={CardExpiryDate=0124}
{
    "KeyArn": "arn:aws:payment-cryptography:us-west-2:123412341234:key/42cdc4ocf45mg54h",
    "KeyCheckValue": "B2DD4E",
    "ValidationData": "343"
}

I take note of the three digits in the ValidationData property. When processing a payment, I can verify that the card data value is correct:

aws payment-cryptography-data verify-card-validation-data \
    --key-identifier alias/my-key \
    --primary-account-number=171234567890123 \
    --verification-attributes CardVerificationValue2={CardExpiryDate=0124} \
    --validation-data 343
{
    "KeyArn": "arn:aws:payment-cryptography:us-west-2:123412341234:key/42cdc4ocf45mg54h",
    "KeyCheckValue": "B2DD4E"
}

The verification is successful, and in return I get back the same KeyCheckValue as when I generated the validation data.

As you might expect, if I use the wrong validation data, the verification is not successful, and I get back an error:

aws payment-cryptography-data verify-card-validation-data \
    --key-identifier alias/my-key \
    --primary-account-number=171234567890123 \
    --verification-attributes CardVerificationValue2={CardExpiryDate=0124} \
    --validation-data 999

An error occurred (com.amazonaws.paymentcryptography.exception#VerificationFailedException)
when calling the VerifyCardValidationData operation:
Card validation data verification failed

In the AWS Payment Cryptography console, I choose View Keys to see the list of keys.

Console screenshot.

Optionally, I can enable more columns, for example, to see the key type (symmetric/asymmetric) and the algorithm used.

Console screenshot.

I choose the key I used in the previous example to get more details. Here, I see the cryptographic configuration, the tags assigned to the key, and the aliases that refer to this key.

Console screenshot.

AWS Payment Cryptography supports many more operations than the ones I showed here. For this walkthrough, I used the AWS CLI. In your applications, you can use AWS Payment Cryptography through any of the AWS SDKs.

Availability and Pricing
AWS Payment Cryptography is available today in the following AWS Regions: US East (N. Virginia) and US West (Oregon).

With AWS Payment Cryptography, you only pay for what you use based on the number of active keys and API calls with no up-front commitment or minimum fee. For more information, see AWS Payment Cryptography pricing.

AWS Payment Cryptography removes your dependencies on dedicated payment HSMs and legacy key management systems, simplifying your integration with AWS native APIs. In addition, by operating the entire payment application in the cloud, you can minimize round-trip communications and latency.

Move your payment processing applications to the cloud with AWS Payment Cryptography.

— Danilo

Announcing the latest AWS Heroes – June 2023

Post Syndicated from Taylor Jacobsen original https://aws.amazon.com/blogs/aws/announcing-the-latest-aws-heroes-june-2023/

AWS Heroes dedicate their time to help others build better and faster on AWS. Heroes support and give back to the community in a variety of ways: contributing to open source projects, organizing AWS Community Days, speaking at conferences, leading workshops, mentoring builders, hosting meetups, and much more.

Please welcome and say hello to our newest AWS Heroes!

AJ Stuyvenberg – Boston, USA

Serverless Hero AJ Stuyvenberg is a Staff Engineer at Datadog, and has been a member of the serverless community since early 2017. His work focuses on serverless and distributed system observability. AJ is an open source author and maintains several projects, which improve the serverless developer experience. He has also spoken at multiple conferences, including AWS re:Invent and AWS Summits, and frequently writes about serverless topics on his blog.

Danielle Heberling – Hillsboro, USA

Serverless Hero Danielle Heberling is a software engineer with a background that includes being a musician, teaching at a K-8 public school, and working in technical support. She’s passionate about building things that make the world a better place, whether that be through social change or a good laugh. When she’s not coding or talking about serverless, you can often find her reaching back to her teaching roots by mentoring folks from underrepresented groups that would like to make a career switch into tech.

Dominik Grzywaczewski – Lublin, Poland

Community Hero Dominik Grzywaczewski is a Senior Cloud Site Reliability Engineer at Chaos Gears with more than 15 years of experience in IT. His primary objective is to assist companies in gaining a deeper understanding of Cloud Computing technologies, and effectively leveraging them to drive faster and more secure innovation. Dominik shares his passion by organizing technical meetups and workshops, and consistently collaborates with AWS community members. He also founded the AWS User Group in Lublin (Poland) and co-organizes the AWS Community Day conference in Warsaw (Poland).

Johannes Koch – Hessen, Germany

DevTools Hero Johannes Koch is a Sr. DevOps Engineer, Developer Experience, GTS at FICO where he contributes to the FICO®️ Platform. He shares his best practices related to Continuous Integration and Continuous Deployment (CI/CD) on his YouTube channel: cicdonaws. Johannes also founded the AWS User Group Bergstrasse, helped to start the AWS Community DACH Förderverein, and is part of the team that organizes the AWS Community Day in the DACH region.

Michael Walmsley – Melbourne, Australia

Serverless Hero Michael Walmsley is a Lead Technology Architect in the myWizard®️ Automation Group at Accenture, where he is focused on building event-driven products in the cloud. He is excited by the AWS Lambda Powertools open-source projects, and has been using and actively contributing to them since 2020. Michael is also a passionate AWS community member in Australia, supporting local meetups and conferences. He helps organize and run the AWS Programming and Tools Meetup in Melbourne, which focuses on running monthly hands-on training workshops that are open to everyone.

Mikey Fan – Beijing, China

Community Hero Mikey Fan is a Cloud-native Application Architect and SDN Developer. Since 2020, he has been actively exploring how to build innovative applications based on AWS EKS, Private 5G, and SD-WAN technology, and then applying them to 5G Edge Computing scenarios. Mikey is also a cloud-computing technology evangelist and an open-source enthusiast. He enjoys contributing code to open-source projects, such as Kubernetes and Tungsten Fabric, and he likes to demo how these open-source technologies can be combined with AWS cloud computing to create greater value.

Ran Isenberg – Kfar Saba, Israel

Serverless Hero Ran Isenberg is a principal software architect at CyberArk, where he designs and builds serverless services. He is passionate about CI/CD and AWS CDK, and has contributed several utilities to the AWS Lambda Powertools open-source project. Ran also maintains numerous serverless related open-source projects on his GitHub account, such as the AWS Lambda cookbook – a serverless service template that gets you started in the serverless world with all of the best practices in seconds.

Sabiha Ali – Dubai, United Arab Emirates

Community Hero Sabiha Ali is a Solutions Architect at ScaleCapacity. She specializes in Amazon Connect, architecting resilient and secure systems in the cloud. As an Amazon Connect Ambassador, she helps businesses enhance their customer experiences. Her unwavering passion for learning has earned her numerous AWS certifications (9X), solidifying her expertise in the field. She became an AWS User Group Leader in Dubai after starting out as an active AWS Community Builder. Sabiha is also committed to empowering women in the tech industry, making her a valued professional and an advocate for change.

Tomasz Dudek – Wroclaw, Poland

Machine Learning Hero Tomasz Dudek works as a Data & AI Team Lead and a Solutions Architect at Chaos Gears. He guides customers on how leveraging machine learning powered solutions can help their businesses thrive. He also designs AWS architectures and manages a data-focused team. Additionally, Tomasz co-organizes the AWS Community Day Poland, and as well as hosts the AWS User Group in his hometown Wroclaw. He often conducts workshops, such as SageMaker Immersion Days, speaks at conferences, and shares his knowledge in the form of short posts on LinkedIn, and longer ones on his blog, ‘MLOps and how you tame it.’

Wojciech Dąbrowski – Katowice, Poland

Community Hero Wojciech Dąbrowski is Head of Cloud Architecture at DTiQ, where he leads the team responsible for the architecture of cloud solutions and the cloud adaptation strategy in the organization. He has been an AWS User Group Silesia leader since 2019, and has managed to organize multiple online and offline meetups. In addition, Wojciech leads workshops and presents cloud computing and software engineering topics at various events.

Learn More

If you’d like to learn more about the new Heroes or connect with a Hero near you, please visit the AWS Heroes website or browse the AWS Heroes Content Library.

— Taylor

A New Set of APIs for Amazon SQS Dead-Letter Queue Redrive

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/a-new-set-of-apis-for-amazon-sqs-dead-letter-queue-redrive/

Today, we launch a new set of APIs for Amazon Simple Queue Service (Amazon SQS). These new APIs allow you to manage dead-letter queue (DLQ) redrive programmatically. You can now use the AWS SDKs or the AWS Command Line Interface (AWS CLI) to programmatically move messages from the DLQ to their original queue, or to a custom queue destination, to attempt to process them again. A DLQ is a queue where Amazon SQS automatically moves messages that are not correctly processed by your consumer application.

To fully appreciate how this new API might help you, let’s have a quick look back at history.

Message queues are an integral part of modern application architectures. They allow developers to decouple services by allowing asynchronous and message-based communications between message producers and consumers. In most systems, messages are persisted in shared storage (the queue) until the consumer processes them. Message queues allow developers to build applications that are resilient to temporary service failure. They help prioritize message processing and scale their fleet of worker nodes that process the messages. Message queues are also popular in event-driven architectures.

Asynchronous message exchange is not new in application architectures. The concept of exchanging messages asynchronously between applications appeared in the 1960s and was first made popular when IBM launched TCAM for OS/360 in 1972. The general adoption came 20 years later with IBM MQ Series in 1993 (now IBM MQ) and when Sun Microsystems released Java Messaging Service (JMS) in 1998, a standard API for Java applications to interact with message queues.

AWS launched Amazon SQS on July 12, 2006. Amazon SQS is a highly scalable, reliable, and elastic queuing service that “just works.” As Werner wrote at the time: “We have chosen a concurrency model where the process working on a message automatically acquires a leased lock on that message; if the message is not deleted before the lease expires, it becomes available for processing again. Makes failure handling very simple.”

On January 29, 2014, we introduced dead-letter queues (DLQ). DLQs help you avoid a message that failed to be processed from staying forever on top of the queue, possibly preventing other messages in the queue from processing. With DLQs, each queue has an associated property telling Amazon SQS how many times a message may be presented for processing (maxReceiveCount). Each message also has an associated receive counter (ReceiveCount). Each time a consumer application picks up a message for processing, the message receive count is incremented by 1. When ReceiveCount > maxReceiveCount, Amazon SQS moves the message to your designated DLQ for human analysis and debugging. You generally associate alarms with the DLQ to send notifications when such events happen. Typical reasons to move a message to the DLQ are because they are incorrectly formatted, there are bugs in the consumer application, or it takes too long to process the message.

At AWS re:Invent 2021, AWS announced dead-letter queue redrive on the Amazon SQS console. The redrive addresses the second part of the failed message lifecycle. It allows you to reinject the message in its original queue to attempt processing it again. After the consumer application is fixed and ready to consume the failed messages, you can redrive the messages from the DLQ back in the source queue or a customized queue destination. It just requires a couple of clicks on the console.

Today, we are adding APIs allowing you to write applications and scripts that handle the redrive programmatically. There is no longer a need to have a human clicking on the console. Using the API increases the scalability of your processes and reduces the risk of human error.

Let’s See It in Action
To try out this new API, I open a terminal for a command-line only demo. Before I get started, I make sure I have the latest version of the AWS CLI. On macOS I enter brew upgrade awscli.

I first create two queues. One is the dead-letter queue, and the other is my application queue:

# First, I create the dead-letter queue (notice the -dlq I choose to add at the end of the queue name)
➜ ~ aws sqs create-queue \
            --queue-name awsnewsblog-dlq                                            
{
    "QueueUrl": "https://sqs.us-east-2.amazonaws.com/012345678900/awsnewsblog-dlq"
}

# second, I retrieve the Arn of the queue I just created
➜  ~ aws sqs get-queue-attributes \
             --queue-url https://sqs.us-east-2.amazonaws.com/012345678900/awsnewsblog-dlq \
             --attribute-names QueueArn
{
    "Attributes": {
        "QueueArn": "arn:aws:sqs:us-east-2:012345678900:awsnewsblog-dlq"
    }
}

# Third, I create the application queue. I enter a redrive policy: post messages in the DLQ after three delivery attempts
➜  ~ aws sqs create-queue \
             --queue-name awsnewsblog \
             --attributes '{"RedrivePolicy": "{\"deadLetterTargetArn\":\"arn:aws:sqs:us-east-2:012345678900:awsnewsblog-dlq\",\"maxReceiveCount\":\"3\"}"}' 
{
    "QueueUrl": "https://sqs.us-east-2.amazonaws.com/012345678900/awsnewsblog"
}

Now that the two queues are ready, I post a message to the application queue:

➜ ~ aws sqs send-message \
            --queue-url https://sqs.us-east-2.amazonaws.com/012345678900/awsnewsblog \
            --message-body "Hello World"
{
"MD5OfMessageBody": "b10a8db164e0754105b7a99be72e3fe5",
"MessageId": "fdc26778-ce9a-4782-9e33-ae73877cfcb2"
}

Next, I consume the message, but I don’t delete it from the queue. This simulates a crash in the message consumer application. Message consumers are supposed to delete the message after successful processing. I set the maxReceivedCount property to 3 when I entered the redrivePolicy. I therefore repeat this operation three times to force Amazon SQS to move the message to the dead-letter queue after three delivery attempts. The default visibility timeout is 30 seconds, so I have to wait 30 seconds or more between the retries.

➜ ~ aws sqs receive-message \
            --queue-url https://sqs.us-east-2.amazonaws.com/012345678900/awsnewsblog
{
"Messages": [
{
"MessageId": "fdc26778-ce9a-4782-9e33-ae73877cfcb2",
"ReceiptHandle": "AQEBP8yOfgBlnjlkGXjyeLROiY7xg7cZ6Znq8Aoa0d3Ar4uvTLPrHZptNotNfKRK25xm+IU8ebD3kDwZ9lja6JYs/t1kBlwiNO6TBACN5srAb/WggQiAAkYl045Tx3CvsOypbJA3y8U+MyEOQRwIz6G85i7MnR8RgKTlhOzOZOVACXC4W8J9GADaQquFaS1wVeM9VDsOxds1hDZLL0j33PIAkIrG016LOQ4sAntH0DOlEKIWZjvZIQGdlRJS65PJu+I/Ka1UPHGiFt9f8m3SR+Y34/ttRWpQANlXQi5ByA47N8UfcpFXXB5L30cUmoDtKucPewsJNG2zRCteR0bQczMMAmOPujsKq70UGOT8X2gEv2LfhlY7+5n8z3yew8sdBjWhVSegrgj6Yzwoc4kXiMddMg==",
"MD5OfBody": "b10a8db164e0754105b7a99be72e3fe5",
"Body": "Hello World"
}
]
}

# wait 30 seconds,
# then repeat two times (for a total of three receive-message API calls)

After three processing attempts, the message is not in the queue anymore:

➜  ~ aws sqs receive-message \
             --queue-url  https://sqs.us-east-2.amazonaws.com/012345678900/awsnewsblog
{
    "Messages": []
}

The message has been moved to the dead-letter queue. I check the DLQ to confirm (notice the queue URL ending with -dlq):

➜  ~ aws sqs receive-message \
             --queue-url  https://sqs.us-east-2.amazonaws.com/012345678900/awsnewsblog-dlq
{
    "Messages": [
        {
            "MessageId": "fdc26778-ce9a-4782-9e33-ae73877cfcb2",
            "ReceiptHandle": "AQEBCLtBMoZYVMMq7fUGNHeCliqE3mFXnkuJ+nOXLK1++uoXWBG31nDejCpxElmiBZWfbcfGJrEdKj4P9HJdrQMYDbeSqB+u1ZlB7CYzQBiQps4SEG0biEoubwqjQbmDZlPrmkFsnYgLD98D1XYWk/Ik6Z2n/wxDo9ko9rbZ15izK5RFnbwveNy8dfc6ireqVB1EGbeGkHcweHGuoeKWXEab1ynZWhNqZsQgCR6pWRkgtn59lJcLv4cJ4UMewNzvt7tMHH69GvVjXdYDYvJJI2vj+6RHvcvSHWWhTNT+CuPEXguVNuNrSya8gho1fCnKpVwQre6HhMlLPjY4wvn/tXY7+5rmte9eXagCqLQXaENB2R7qWNVPiWRIJy8/cTf37NLYVzBom030DNJlH9EeceRhCQ==",
            "MD5OfBody": "b10a8db164e0754105b7a99be72e3fe5",
            "Body": "Hello World"
        }
    ]
}

Now that the setup is ready, let’s programmatically redrive the message to its original queue. Let’s assume I understand why the consumer didn’t correctly process the message and that I fixed the consumer application code. I use start-message-move-task on the DLQ to start the asynchronous redrive. There is an optional attribute (MaxNumberOfMessagesPerSecond) to control the velocity of the redrive:

➜ ~ aws sqs start-message-move-task \
            --source-arn arn:aws:sqs:us-east-2:012345678900:awsnewsblog-dlq
{
    "TaskHandle": "eyJ0YXNrSWQiOiI4ZGJmNjBiMy00MmUwLTQzYTYtYjg4Zi1iMTZjYWRjY2FkNmEiLCJzb3VyY2VBcm4iOiJhcm46YXdzOnNxczp1cy1lYXN0LTI6NDg2NjUyMDY2NjkzOmF3c25ld3NibG9nLWRscSJ9"
}

I can list and check status the of the move tasks I initiated with list-message-move-tasks or cancel a running task by calling the cancel-message-move-task API:

➜ ~ aws sqs list-message-move-tasks \
            --source-arn arn:aws:sqs:us-east-2:012345678900:awsnewsblog-dlq
{
    "Results": [
        {
            "Status": "COMPLETED",
            "SourceArn": "arn:aws:sqs:us-east-2:012345678900:awsnewsblog-dlq",
            "ApproximateNumberOfMessagesMoved": 1,
            "ApproximateNumberOfMessagesToMove": 1,
            "StartedTimestamp": 1684135792239
        }
    ]
}

Now my application can consume the message again from the application queue:

➜  ~ aws sqs receive-message \
             --queue-url  https://sqs.us-east-2.amazonaws.com/012345678900/awsnewsblog                                   
{
    "Messages": [
        {
            "MessageId": "a7ae83ca-cde4-48bf-b822-3d4bc1f4dcae",
            "ReceiptHandle": "AQEB9a+Dm2nvb3VUn9+46j9UsDidU/W6qFwJtXtNWTyfoSDOKT7h73e6ctT9RVZysEw3qqzJOx1cxblTTOSrYwwwoBA2qoJMGsqsrsRGGYojBvf9X8hqi8B8MHn9rTm8diJ2wT2b7WC+TDrx3zIvUeiSEkP+EhqyYOvOs7Q9aETR+Uz02kQxZ/cUJWsN4MMSXBejwW+c5ivv5uQtpfUrfZuCWa9B9O67Kj/q52clriPHpcqCCfJwFBSZkGTXYwTpnjxD4QM7DPS+xVeVfTyM7DsKCAOtpvFBmX5m4UNKT6TROgCnGxTRglUSMWQp8ufVxXiaUyM1dwqxYekM9uX/RCb01gEyCZHas4jeNRV5nUJlhBkkqPlw3i6w9Uuc2y9nH0Df8nH3g7KTXo4lv5Bl3ayh9w==",
            "MD5OfBody": "b10a8db164e0754105b7a99be72e3fe5",
            "Body": "Hello World"
        }
    ]
}

Availability
DLQ redrive APIs are available today in all commercial Regions where Amazon SQS is available.

Redriving the messages from the dead-letter queue to the source queue or a custom destination queue generates additional API calls billed based on existing pricing (starting at $0.40 per million API calls, after the first million, which is free every month). Amazon SQS batches the messages while redriving them from one queue to another. This makes moving messages from one queue to another a simple and low-cost option.

To learn more about DLQ and DLQ redrive, check our documentation.

Remember that we live in an asynchronous world—so should your applications. Get started today and write your first redrive application.

— seb

AWS Week in Review – Amazon Security Lake Now GA, New Actions on AWS Fault Injection Simulator, and More – June 5, 2023

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/aws-week-in-review-amazon-security-lake-now-ga-new-actions-on-aws-fault-injection-simulator-and-more-june-5-2023/

Last Wednesday, I traveled to Cape Town to speak at the .Net Developer User Group. My colleague Francois Bouteruche also gave a talk but joined virtually. I enjoyed my time there—what an amazing community! Join the group in order to learn about upcoming events.

Now onto the AWS updates from last week. There was a lot of news related to AWS, and I have compiled a few announcements you need to know. Let’s get started!

Last Week’s Launches
Here are a few launches from last week that you might have missed:

Amazon Security Lake is now Generally Available – This service automatically centralizes security data from AWS environments, SaaS providers, on-premises environments, and cloud sources into a purpose-built data lake stored in your account, making it easier to analyze security data, gain a more comprehensive understanding of security across your entire organization, and improve the protection of your workloads, applications, and data. Read more in Channy’s post announcing the preview of Security Lake.

New AWS Direct Connect Location in Santiago, Chile – The AWS Direct Connect service lets you create a dedicated network connection to AWS. With this service, you can build hybrid networks by linking your AWS and on-premises networks to build applications that span environments without compromising performance. Last week we announced the opening of a new AWS Direct Connect location in Santiago, Chile. This new Santiago location offers dedicated 1 Gbps and 10 Gbps connections, with MACsec encryption available for 10 Gbps. For more information on over 115 Direct Connect locations worldwide, visit the locations section of the Direct Connect product detail pages.

New actions on AWS Fault Injection Simulator for Amazon EKS and Amazon ECS – Had it not been for Adrian Hornsby’s LinkedIn post I would have missed this announcement. We announced the expanded support of AWS Fault Injection Simulator (FIS) for Amazon Elastic Kubernetes Service (EKS) and Amazon Elastic Container Service (ECS). This expanded support adds additional AWS FIS actions for Amazon EKS and Amazon ECS. Learn more about Amazon ECS task actions here, and Amazon EKS pod actions here.

Other AWS News
A few more news items and blog posts you might have missed:
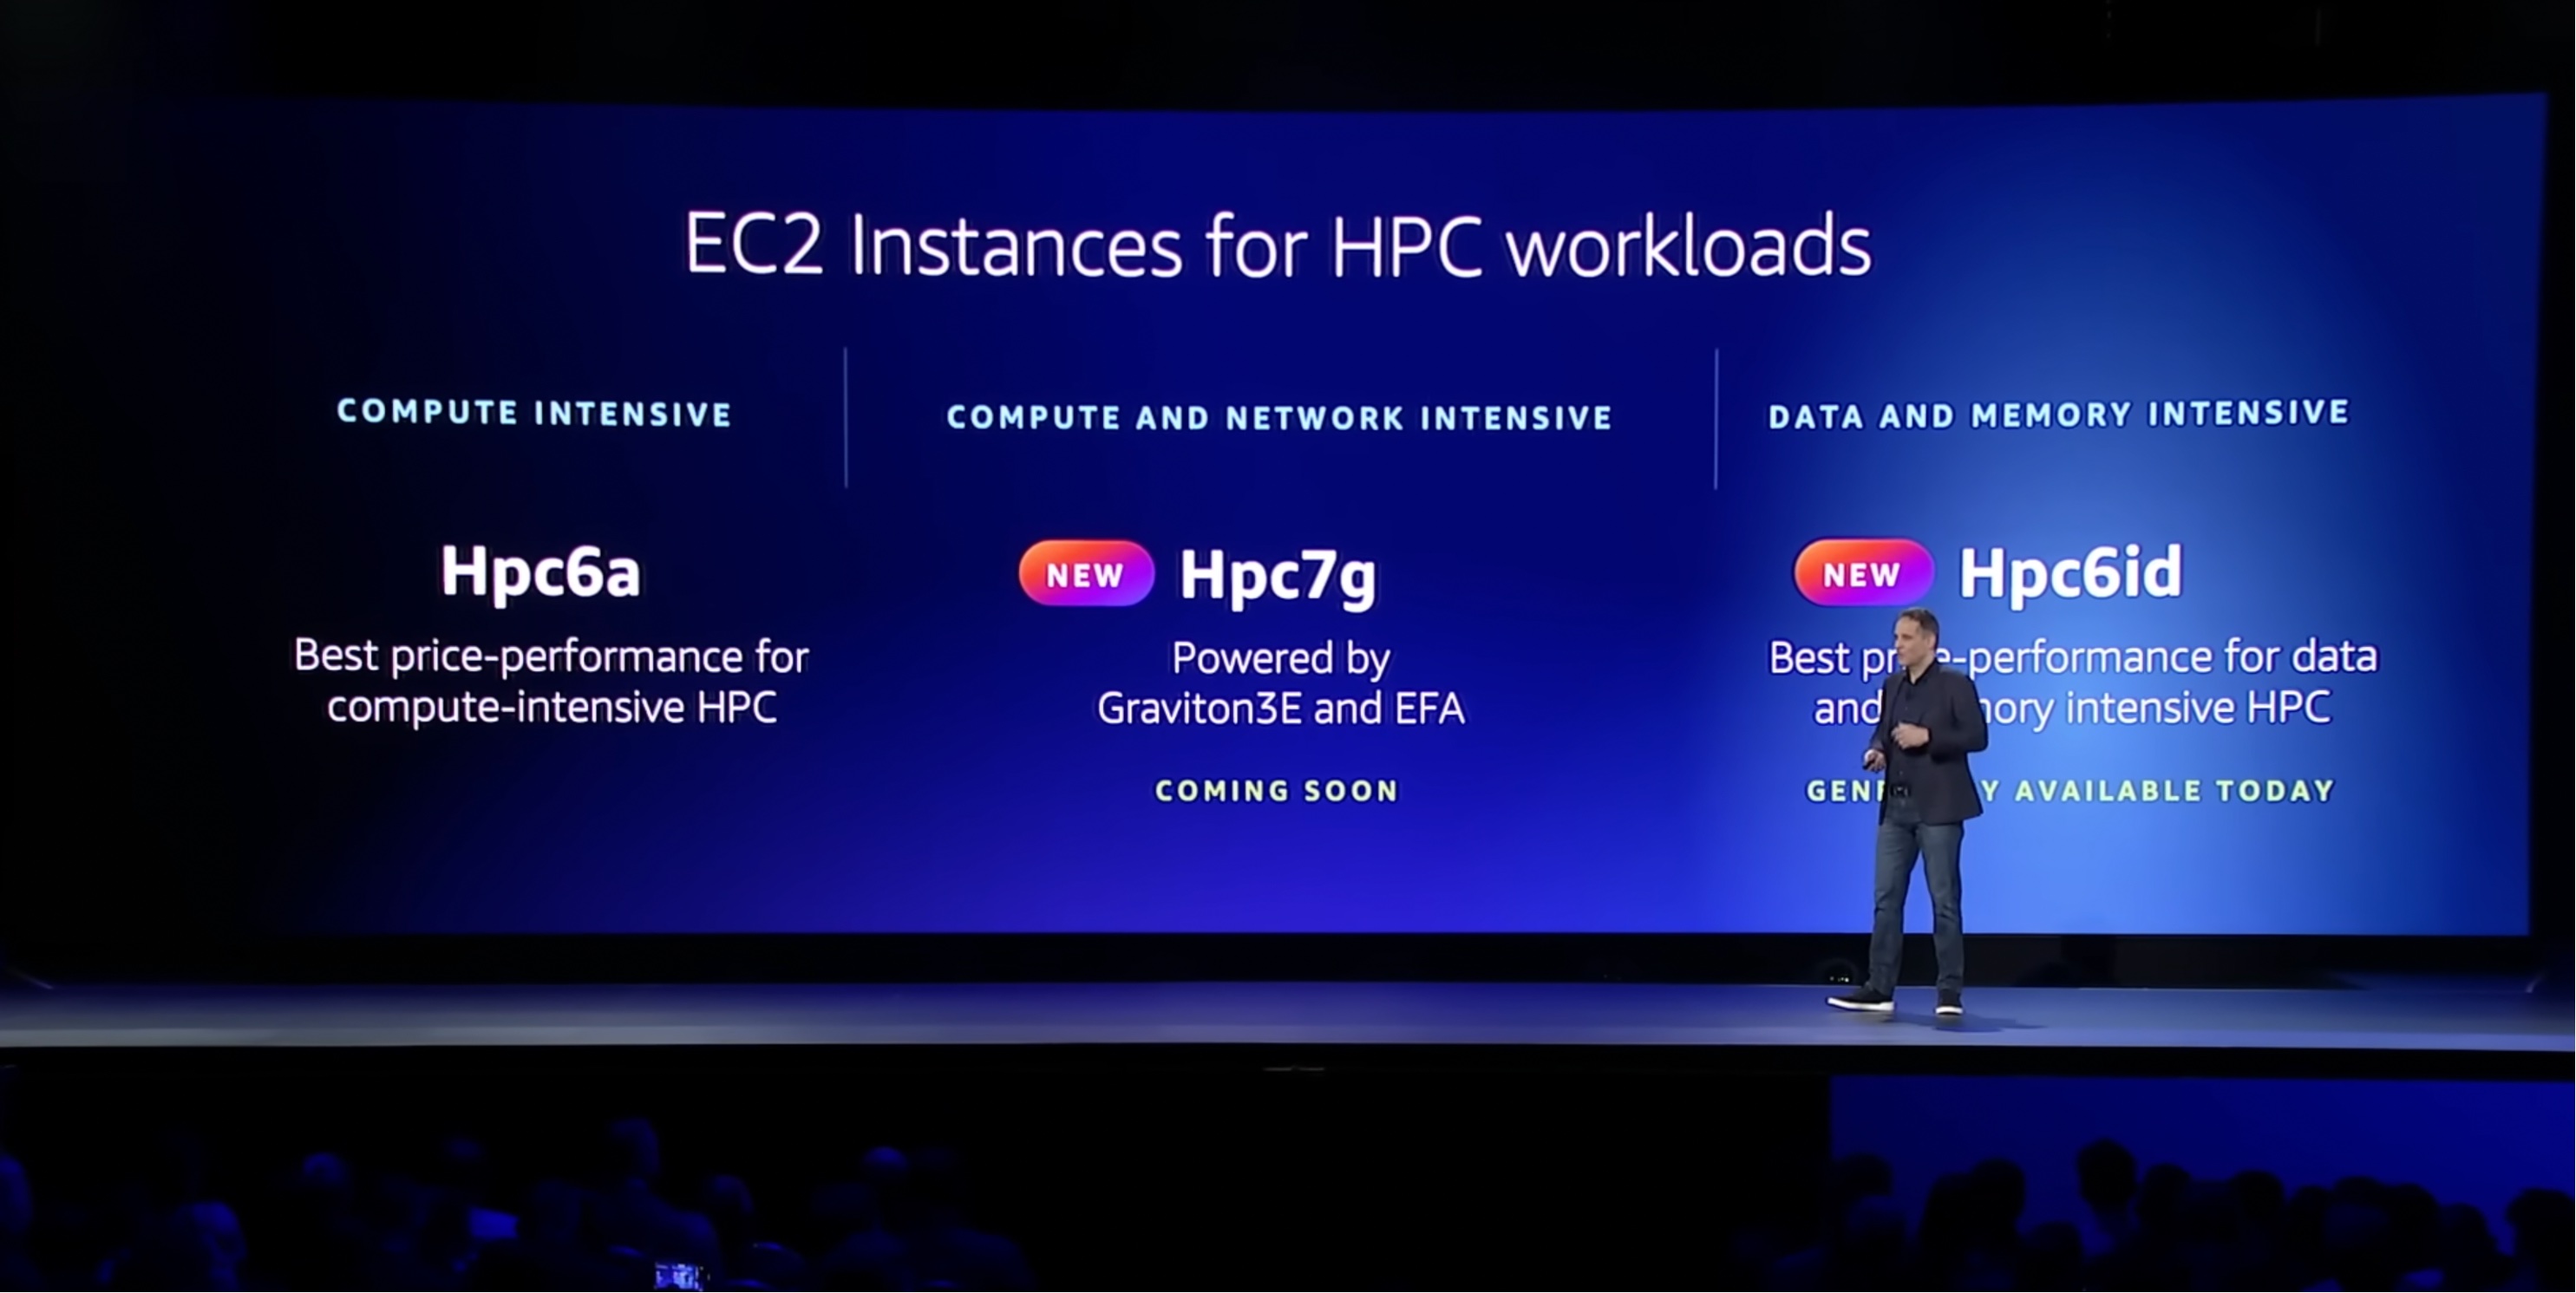
Autodesk Uses Sagemaker to Improve Observability – One of our customers, Autodesk, used AWS services including Amazon Sagemaker, Amazon Kinesis, and Amazon API Gateway to build a platform that enables development and deployment of near-real time personalization experiments by modeling and responding to user behavior data. All this delivered a dynamic, personalized experience for Autodesk’s customers. Read more about the story at AWS Customer Stories.

AWS DMS Serverless – We announced AWS DMS Serverless which lets you automatically provision and scale capacity for migration and data replication. Donnie wrote about this announcement here.

For AWS open-source news and updates, check out the latest newsletter curated by my colleague Ricardo Sueiras to bring you the most recent updates on open-source projects, posts, events, and more.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Upcoming AWS Events
We have the following upcoming events. These give you the opportunity to meet with other tech enthusiasts and learn:

AWS Silicon Innovation Day (June 21) – A one-day virtual event that will allow you to understand AWS Silicon and how you can use AWS’s unique silicon offerings to innovate. Learn more and register here.

AWS Global Summits – Sign up for the AWS Summit closest to where you live: London (June 7), Washington, DC (June 7–8), Toronto (June 14).

AWS Community Days – Join these community-led conferences where event logistics and content are planned, sourced, and delivered by community leaders: Chicago, Illinois (June 15), and Chile (July 1).

And with that, I end my very first Week in Review post, and this was such fun to write. Come back next Monday for another Week in Review!

– Veliswa x

This post is part of our Week in Review series. Check back each week for a quick roundup of interesting news and announcements from AWS!