Tag Archives: Technical How-to

How SafetyCulture scales unpredictable dbt Cloud workloads in a cost-effective manner with Amazon Redshift

Post Syndicated from Anish Moorjani original https://aws.amazon.com/blogs/big-data/how-safetyculture-scales-unpredictable-dbt-cloud-workloads-in-a-cost-effective-manner-with-amazon-redshift/

This post is co-written by Anish Moorjani, Data Engineer at SafetyCulture.

SafetyCulture is a global technology company that puts the power of continuous improvement into everyone’s hands. Its operations platform unlocks the power of observation at scale, giving leaders visibility and workers a voice in driving quality, efficiency, and safety improvements.

Amazon Redshift is a fully managed data warehouse service that tens of thousands of customers use to manage analytics at scale. Together with price-performance, Amazon Redshift enables you to use your data to acquire new insights for your business and customers while keeping costs low.

In this post, we share the solution SafetyCulture used to scale unpredictable dbt Cloud workloads in a cost-effective manner with Amazon Redshift.

Use case

SafetyCulture runs an Amazon Redshift provisioned cluster to support unpredictable and predictable workloads. A source of unpredictable workloads is dbt Cloud, which SafetyCulture uses to manage data transformations in the form of models. Whenever models are created or modified, a dbt Cloud CI job is triggered to test the models by materializing the models in Amazon Redshift. To balance the needs of unpredictable and predictable workloads, SafetyCulture used Amazon Redshift workload management (WLM) to flexibly manage workload priorities.

With plans for further growth in dbt Cloud workloads, SafetyCulture needed a solution that does the following:

  • Caters for unpredictable workloads in a cost-effective manner
  • Separates unpredictable workloads from predictable workloads to scale compute resources independently
  • Continues to allow models to be created and modified based on production data

Solution overview

The solution SafetyCulture used is comprised of Amazon Redshift Serverless and Amazon Redshift Data Sharing, along with the existing Amazon Redshift provisioned cluster.

Amazon Redshift Serverless caters to unpredictable workloads in a cost-effective manner because compute cost is not incurred when there is no workload. You pay only for what you use. In addition, moving unpredictable workloads into a separate Amazon Redshift data warehouse allows each Amazon Redshift data warehouse to scale resources independently.

Amazon Redshift Data Sharing enables data access across Amazon Redshift data warehouses without having to copy or move data. Therefore, when a workload is moved from one Amazon Redshift data warehouse to another, the workload can continue to access data in the initial Amazon Redshift data warehouse.

The following figure shows the solution and workflow steps:

  1. We create a serverless instance to cater for unpredictable workloads. Refer to Managing Amazon Redshift Serverless using the console for setup steps.
  2. We create a datashare called prod_datashare to allow the serverless instance access to data in the provisioned cluster. Refer to Getting started data sharing using the console for setup steps. Database names are identical to allow queries with full path notation database_name.schema_name.object_name to run seamlessly in both data warehouses.
  3. dbt Cloud connects to the serverless instance and models, created or modified, are tested by being materialized in the default database dev, in either each users’ personal schema or a pull request related schema. Instead of dev, you can use a different database designated for testing. Refer to Connect dbt Cloud to Redshift for setup steps.
  4. You can query materialized models in the serverless instance with materialized models in the provisioned cluster to validate changes. After you validate the changes, you can implement models in the serverless instance in the provisioned cluster.

Outcome

SafetyCulture carried out the steps to create the serverless instance and datashare, with integration to dbt Cloud, with ease. SafetyCulture also successfully ran its dbt project with all seeds, models, and snapshots materialized into the serverless instance via run commands from the dbt Cloud IDE and dbt Cloud CI jobs.

Regarding performance, SafetyCulture observed dbt Cloud workloads completing on average 60% faster in the serverless instance. Better performance could be attributed to two areas:

  • Amazon Redshift Serverless measures compute capacity using Redshift Processing Units (RPUs). Because it costs the same to run 64 RPUs in 10 minutes and 128 RPUs in 5 minutes, having a higher number of RPUs to complete a workload sooner was preferred.
  • With dbt Cloud workloads isolated on the serverless instance, dbt Cloud was configured with more threads to allow materialization of more models at once.

To determine cost, you can perform an estimation. 128 RPUs provides approximately the same amount of memory that an ra3.4xlarge 21-node provisioned cluster provides. In US East (N. Virginia), the cost of running a serverless instance with 128 RPUs is $48 hourly ($0.375 per RPU hour * 128 RPUs). In the same Region, the cost of running an ra3.4xlarge 21-node provisioned cluster on demand is $68.46 hourly ($3.26 per node hour * 21 nodes). Therefore, an accumulated hour of unpredictable workloads on a serverless instance is 29% more cost-effective than an on-demand provisioned cluster. Calculations in this example should be recalculated when performing future cost estimations because prices may change over time.

Learnings

SafetyCulture had two key learnings to better integrate dbt with Amazon Redshift, which can be helpful for similar implementations.

First, when integrating dbt with an Amazon Redshift datashare, configure INCLUDENEW=True to ease management of database objects in a schema:

ALTER DATASHARE datashare_name SET INCLUDENEW = TRUE FOR SCHEMA schema;

For example, assume the model customers.sql is materialized by dbt as the view customers. Next, customers is added to a datashare. When customers.sql is modified and rematerialized by dbt, dbt creates a new view with a temporary name, drops customers, and renames the new view to customers. Although the new view carries the same name, it’s a new database object that wasn’t added to the datashare. Therefore, customers is no longer found in the datashare.

Configuring INCLUDENEW=True allows new database objects to be automatically added to the datashare. An alternative to configuring INCLUDENEW=True and providing more granular control is the use of dbt post-hook.

Second, when integrating dbt with more than one Amazon Redshift data warehouse, define sources with database to aid dbt in evaluating the right database.

For example, assume a dbt project is used across two dbt Cloud environments to isolate production and test workloads. The dbt Cloud environment for production workloads is configured with the default database prod_db and connects to a provisioned cluster. The dbt Cloud environment for test workloads is configured with the default database dev and connects to a serverless instance. In addition, the provisioned cluster contains the table prod_db.raw_data.sales, which is made available to the serverless instance via a datashare as prod_db′.raw_data.sales.

When dbt compiles a model containing the source {{ source('raw_data', 'sales') }}, the source is evaluated as database.raw_data.sales. If database is not defined for sources, dbt sets the database to the configured environment’s default database. Therefore, the dbt Cloud environment connecting to the provisioned cluster evaluates the source as prod_db.raw_data.sales, while the dbt Cloud environment connecting to the serverless instance evaluates the source as dev.raw_data.sales, which is incorrect.

Defining database for sources allows dbt to consistently evaluate the right database across different dbt Cloud environments, because it removes ambiguity.

Conclusion

After testing Amazon Redshift Serverless and Data Sharing, SafetyCulture is satisfied with the result and has started productionalizing the solution.

“The PoC showed the vast potential of Redshift Serverless in our infrastructure,” says Thiago Baldim, Data Engineer Team Lead at SafetyCulture. “We could migrate our pipelines to support Redshift Serverless with simple changes to the standards we were using in our dbt. The outcome provided a clear picture of the potential implementations we could do, decoupling the workload entirely by teams and users and providing the right level of computation power that is fast and reliable.”

Although this post specifically targets unpredictable workloads from dbt Cloud, the solution is also relevant for other unpredictable workloads, including ad hoc queries from dashboards. Start exploring Amazon Redshift Serverless for your unpredictable workloads today.


About the authors

Anish Moorjani is a Data Engineer in the Data and Analytics team at SafetyCulture. He helps SafetyCulture’s analytics infrastructure scale with the exponential increase in the volume and variety of data.

Randy Chng is an Analytics Solutions Architect at Amazon Web Services. He works with customers to accelerate the solution of their key business problems.

Role-based access control in Amazon OpenSearch Service via SAML integration with AWS IAM Identity Center

Post Syndicated from Scott Chang original https://aws.amazon.com/blogs/big-data/role-based-access-control-in-amazon-opensearch-service-via-saml-integration-with-aws-iam-identity-center/

Amazon OpenSearch Service is a managed service that makes it simple to secure, deploy, and operate OpenSearch clusters at scale in the AWS Cloud. AWS IAM Identity Center (successor to AWS Single Sign-On) helps you securely create or connect your workforce identities and manage their access centrally across AWS accounts and applications. To build a strong least-privilege security posture, customers also wanted fine-grained access control to manage dashboard permission by user role. In this post, we demonstrate a step-by-step procedure to implement IAM Identity Center to OpenSearch Service via native SAML integration, and configure role-based access control in OpenSearch Dashboards by using group attributes in IAM Identity Center. You can follow the steps in this post to achieve both authentication and authorization for OpenSearch Service based on the groups configured in IAM Identity Center.

Solution overview

Let’s review how to map users and groups in IAM Identity Center to OpenSearch Service security roles. Backend roles in OpenSearch Service are used to map external identities or attributes of workgroups to pre-defined OpenSearch Service security roles.

The following diagram shows the solution architecture. Create two groups, assign a user to each group and edit attribute mappings in IAM Identity Center. If you have integrated IAM Identity Center with your Identity Provider (IdP), you can use existing users and groups mapped to your IdP for this test. The solution uses two roles: all_access for administrators, and alerting_full_access for developers who are only allowed to manage OpenSearch Service alerts. You can set up backend role mapping in OpenSearch Dashboards by group ID. Based on the following diagram, you can map the role all_access to the group Admin, and alerting_full_access to Developer. User janedoe is in the group Admin, and user johnstiles is in the group Developer.

Then you will log in as each user to verify the access control by looking at the different dashboard views.

Let’s get started!

Prerequisites

Complete the following prerequisite steps:

  1. Have an AWS account.
  2. Have an Amazon OpenSearch Service domain.
  3. Enable IAM Identity Center in the same Region as the OpenSearch Service domain.
  4. Test your users in IAM Identity Center (to create users, refer to Add users).

Enable SAML in Amazon OpenSearch Service and copy SAML parameters

To configure SAML in OpenSearch Service, complete the following steps:

  1. On the OpenSearch Service console, choose Domains in the navigation pane.
  2. Choose your domain.
  3. On the Security configuration tab, confirm that Fine-grained access control is enabled.
  4. On the Actions menu, choose Edit security configuration.
  5. Select Enable SAML authentication.

You can also configure SAML during domain creation if you are creating a new OpenSearch domain. For more information, refer to SAML authentication for OpenSearch Dashboards.

  1. Copy the values for Service provider entity ID and IdP-Initiated SSO URL.

Create a SAML application in IAM Identity Center

To create a SAML application in IAM Identity Center, complete the following steps:

  1. On the IAM Identity Center console, choose Applications in the navigation pane.
  2. Choose Add application.
  3. Select Add customer SAML 2.0 application, then choose Next.
  4. Enter your application name for Display name.
  5. Under IAM Identity Center metadata, choose Download to download the SAML metadata file.
  6. Under Application metadata, select Manually type your metadata values.
  7. For Application ACS URL, enter the IdP-initiated URL you copied earlier.
  8. For Application SAML audience, enter the service provider entity ID you copied earlier.
  9. Choose Submit.
  10. On the Actions menu, choose Edit attribute mappings.
  11. Create attributes and map the following values:
    1. Subject map to ${user:email}, the format is emailAddress.
    2. Role map to ${user:groups}, the format is unspecified.
  12. Choose Save changes.
  13. On the IAM Identity Center console, choose Groups in the navigation pane.
  14. Create two groups: Developer and Admin.
  15. Assign user janedoe to the group Admin.
  16. Assign user johnstiles to the group Developer.
  17. Open the Admin group and copy the group ID.

Finish SAML configuration and map the SAML primary backend role

To complete your SAML configuration and map the SAML primary backend role, complete the following steps:

  1. On the OpenSearch Service console, choose Domains in the navigation pane.
  2. Open your domain and choose Edit security configuration.
  3. Under SAML authentication for OpenSearch Dashboards/Kibana, for Import IdP metadata, choose Import from XML file.
  4. Upload the IdP metadata downloaded from the IAM Identity Center metadata file.

The IdP entity ID will be auto populated.

  1. Under SAML master backend role, enter the group ID of the Admin group you copied earlier.
  2. For Roles key, enter Role for the SAML assertion.

This is because we defined and mapped Role to ${user:groups} as a SAML attribute in IAM Identity Center.

  1. Choose Save changes.

Configure backend role mapping for the Developer group

You have completely integrated IAM Identity Center with OpenSearch Service and mapped the Admin group as the primary role (all_access) in OpenSearch Service. Now you will log in to OpenSearch Dashboards as Admin and configure mapping for the Developer group.

There are two ways to log in to OpenSearch Dashboards:

  • OpenSearch Dashboards URL – On the OpenSearch Service console, navigate to your domain and choose the Dashboards URL under General Information. (For example, https://opensearch-domain-name-random-keys.us-west-2.es.amazonaws.com/_dashboards)
  • AWS access portal URL – On the IAM Identity Center console, choose Dashboard in the navigation pane and choose the access portal URL under Settings summary. (For example, https://d-1234567abc.awsapps.com/start)

Complete the following steps:

  1. Log in as the user in the Admin group (janedoe).
  2. Choose the tile for your OpenSearch Service application to be redirected to OpenSearch Dashboards.
  3. Choose the menu icon, then choose Security, Roles.
  4. Choose the alerting_full_access role and on the Mapped users tab, choose Manage mapping.
  5. For Backend roles, enter the group ID of Developer.
  6. Choose Map to apply the change.

Now you have successfully mapped the Developer group to the alerting_full_access role in OpenSearch Service.

Verify permissions

To verify permissions, complete the following steps:

  1. Log out of the Admin account in OpenSearch Service as log in as a Developer user.
  2. Choose the OpenSearch Service application tile to be redirected to OpenSearch Dashboards.

You can see there are only alerting related features available on the drop-down menu. This Developer user can’t see all of the Admin features, such as Security.

Clean up

After you test the solution, remember to delete all of the resources you created to avoid incurring future charges:

  1. Delete your Amazon OpenSearch Service domain.
  2. Delete the SAML application, users, and groups in IAM Identity Center.

Conclusion

In the post, we walked through a solution of how to map roles in Amazon OpenSearch Service to groups in IAM Identity Center by using SAML attributes to achieve role-based access control for accessing OpenSearch Dashboards. We connected IAM Identity Center users to OpenSearch Dashboards, and also mapped predefined OpenSearch Service security roles to IAM Identity Center groups based on group attributes. This makes it easier to manage permissions without updating the mapping when new users belonging to the same workgroup want to log in to OpenSearch Dashboards. You can follow the same procedure to provide fine-grained access to workgroups based on team functions or compliance requirements.


About the Authors

Scott Chang is a Solution Architecture at AWS based in San Francisco. He has over 14 years of hands-on experience in Networking also familiar with Security and Site Reliability Engineering. He works with one of major strategic customers in west region to design highly scalable, innovative and secure cloud solutions.

Muthu Pitchaimani is a Search Specialist with Amazon OpenSearch service. He builds large scale search applications and solutions. Muthu is interested in the topics of networking and security and is based out of Austin, Texas

Build a serverless transactional data lake with Apache Iceberg, Amazon EMR Serverless, and Amazon Athena

Post Syndicated from Houssem Chihoub original https://aws.amazon.com/blogs/big-data/build-a-serverless-transactional-data-lake-with-apache-iceberg-amazon-emr-serverless-and-amazon-athena/

Since the deluge of big data over a decade ago, many organizations have learned to build applications to process and analyze petabytes of data. Data lakes have served as a central repository to store structured and unstructured data at any scale and in various formats. However, as data processing at scale solutions grow, organizations need to build more and more features on top of their data lakes. One important feature is to run different workloads such as business intelligence (BI), Machine Learning (ML), Data Science and data exploration, and Change Data Capture (CDC) of transactional data, without having to maintain multiple copies of data. Additionally, the task of maintaining and managing files in the data lake can be tedious and sometimes complex.

Table formats like Apache Iceberg provide solutions to these issues. They enable transactions on top of data lakes and can simplify data storage, management, ingestion, and processing. These transactional data lakes combine features from both the data lake and the data warehouse. You can simplify your data strategy by running multiple workloads and applications on the same data in the same location. However, using these formats requires building, maintaining, and scaling infrastructure and integration connectors that can be time-consuming, challenging, and costly.

In this post, we show how you can build a serverless transactional data lake with Apache Iceberg on Amazon Simple Storage Service (Amazon S3) using Amazon EMR Serverless and Amazon Athena. We provide an example for data ingestion and querying using an ecommerce sales data lake.

Apache Iceberg overview

Iceberg is an open-source table format that brings the power of SQL tables to big data files. It enables ACID transactions on tables, allowing for concurrent data ingestion, updates, and queries, all while using familiar SQL. Iceberg employs internal metadata management that keeps track of data and empowers a set of rich features at scale. It allows you to time travel and roll back to old versions of committed data transactions, control the table’s schema evolution, easily compact data, and employ hidden partitioning for fast queries.

Iceberg manages files on behalf of the user and unlocks use cases such as:

  • Concurrent data ingestion and querying, including streaming and CDC
  • BI and reporting with expressive simple SQL
  • Empowering ML feature stores and training sets
  • Compliance and regulations workloads, such as GDPR find and forget
  • Reinstating late-arriving data, which is dimensions data arriving later than the fact data. For example, the reason for a flight delay may arrive well after the fact that the fligh is delayed.
  • Tracking data changes and rollback

Build your transactional data lake on AWS

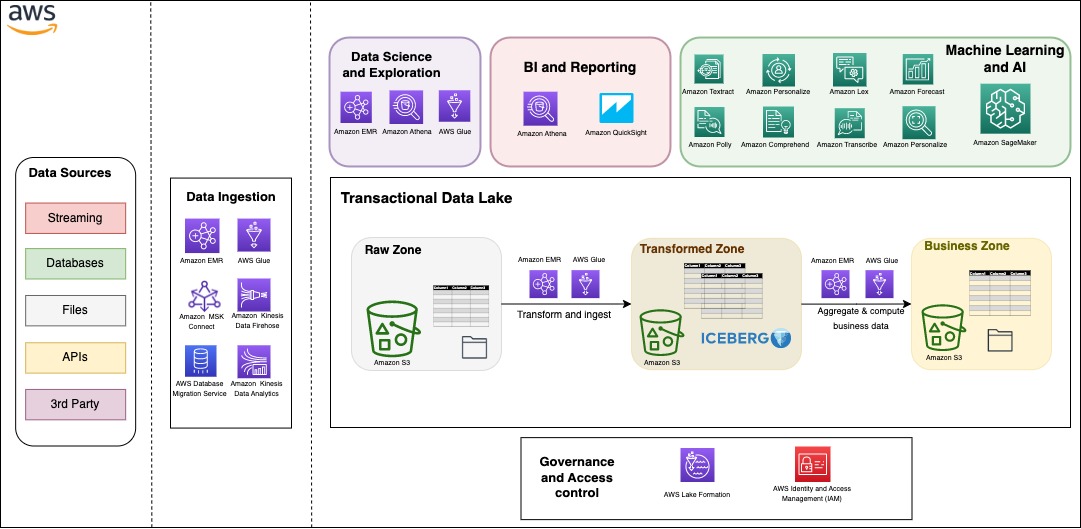
You can build your modern data architecture with a scalable data lake that integrates seamlessly with an Amazon Redshift powered cloud warehouse. Moreover, many customers are looking for an architecture where they can combine the benefits of a data lake and a data warehouse in the same storage location. In the following figure, we show a comprehensive architecture that uses the modern data architecture strategy on AWS to build a fully featured transactional data lake. AWS provides flexibility and a wide breadth of features to ingest data, build AI and ML applications, and run analytics workloads without having to focus on the undifferentiated heavy lifting.

Data can be organized into three different zones, as shown in the following figure. The first zone is the raw zone, where data can be captured from the source as is. The transformed zone is an enterprise-wide zone to host cleaned and transformed data in order to serve multiple teams and use cases. Iceberg provides a table format on top of Amazon S3 in this zone to provide ACID transactions, but also to allow seamless file management and provide time travel and rollback capabilities. The business zone stores data specific to business cases and applications aggregated and computed from data in the transformed zone.

One important aspect to a successful data strategy for any organization is data governance. On AWS, you can implement a thorough governance strategy with fine-grained access control to the data lake with AWS Lake Formation.

Serverless architecture overview

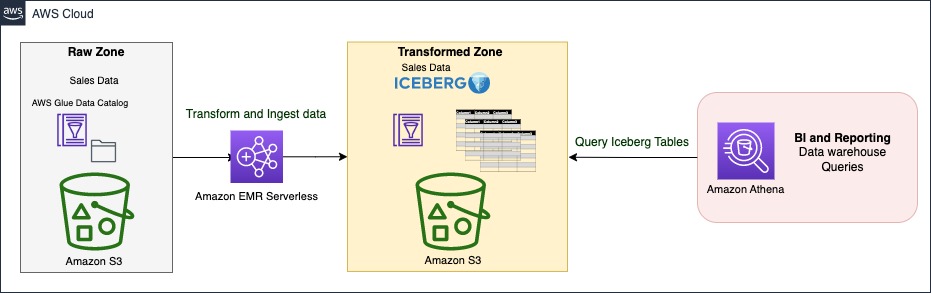
In this section, we show you how to ingest and query data in your transactional data lake in a few steps. EMR Serverless is a serverless option that makes it easy for data analysts and engineers to run Spark-based analytics without configuring, managing, and scaling clusters or servers. You can run your Spark applications without having to plan capacity or provision infrastructure, while paying only for your usage. EMR Serverless supports Iceberg natively to create tables and query, merge, and insert data with Spark. In the following architecture diagram, Spark transformation jobs can load data from the raw zone or source, apply the cleaning and transformation logic, and ingest data in the transformed zone on Iceberg tables. Spark code can run instantaneously on an EMR Serverless application, which we demonstrate later in this post.

The Iceberg table is synced with the AWS Glue Data Catalog. The Data Catalog provides a central location to govern and keep track of the schema and metadata. With Iceberg, ingestion, update, and querying processes can benefit from atomicity, snapshot isolation, and managing concurrency to keep a consistent view of data.

Athena is a serverless, interactive analytics service built on open-source frameworks, supporting open-table and file formats. Athena provides a simplified, flexible way to analyze petabytes of data where it lives. To serve BI and reporting analysis, it allows you to build and run queries on Iceberg tables natively and integrates with a variety of BI tools.

Sales data model

Star schema and its variants are very popular for modeling data in data warehouses. They implement one or more fact tables and dimension tables. The fact table stores the main transactional data from the business logic with foreign keys to dimensional tables. Dimension tables hold additional complementary data to enrich the fact table.

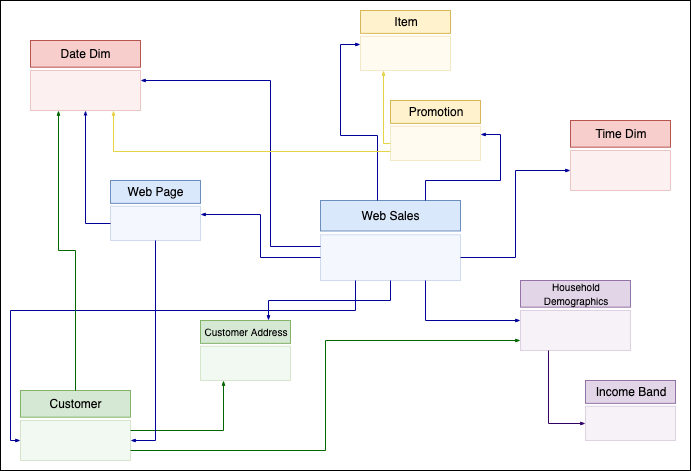
In this post, we take the example of sales data from the TPC-DS benchmark. We zoom in on a subset of the schema with the web_sales fact table, as shown in the following figure. It stores numeric values about sales cost, ship cost, tax, and net profit. Additionally, it has foreign keys to dimensional tables like date_dim, time_dim, customer, and item. These dimensional tables store records that give more details. For instance, you can show when a sale took place by which customer for which item.

Dimension-based models have been used extensively to build data warehouses. In the following sections, we show how to implement such a model on top of Iceberg, providing data warehousing features on top of your data lake, and run different workloads in the same location. We provide a complete example of building a serverless architecture with data ingestion using EMR Serverless and Athena using TPC-DS queries.

Prerequisites

For this walkthrough, you should have the following prerequisites:

  • An AWS account
  • Basic knowledge about data management and SQL

Deploy solution resources with AWS CloudFormation

We provide an AWS CloudFormation template to deploy the data lake stack with the following resources:

  • Two S3 buckets: one for scripts and query results, and one for the data lake storage
  • An Athena workgroup
  • An EMR Serverless application
  • An AWS Glue database and tables on external public S3 buckets of TPC-DS data
  • An AWS Glue database for the data lake
  • An AWS Identity and Access Management (IAM) role and polices

Complete the following steps to create your resources:

  1. Launch the CloudFormation stack:

Launch Button

This automatically launches AWS CloudFormation in your AWS account with the CloudFormation template. It prompts you to sign in as needed.

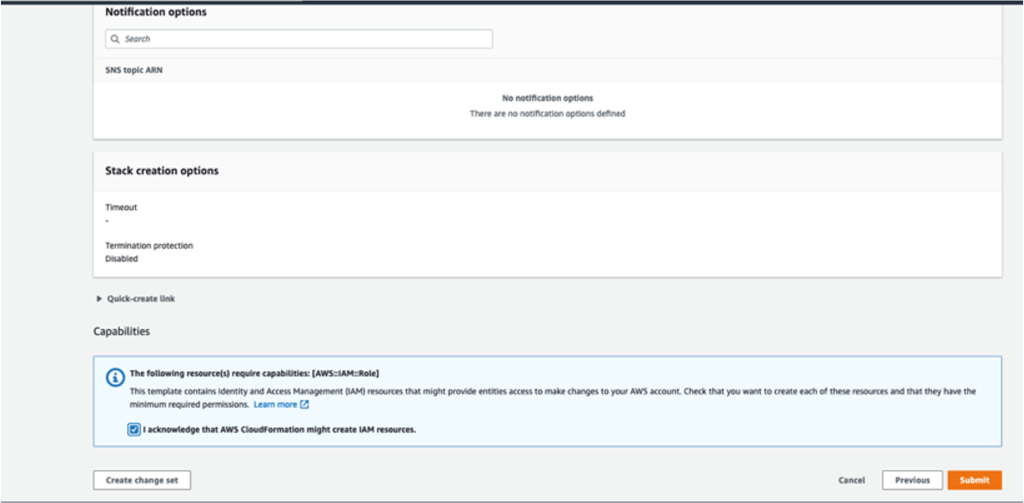
  1. Keep the template settings as is.
  2. Check the I acknowledge that AWS CloudFormation might create IAM resources box.
  3. Choose Submit

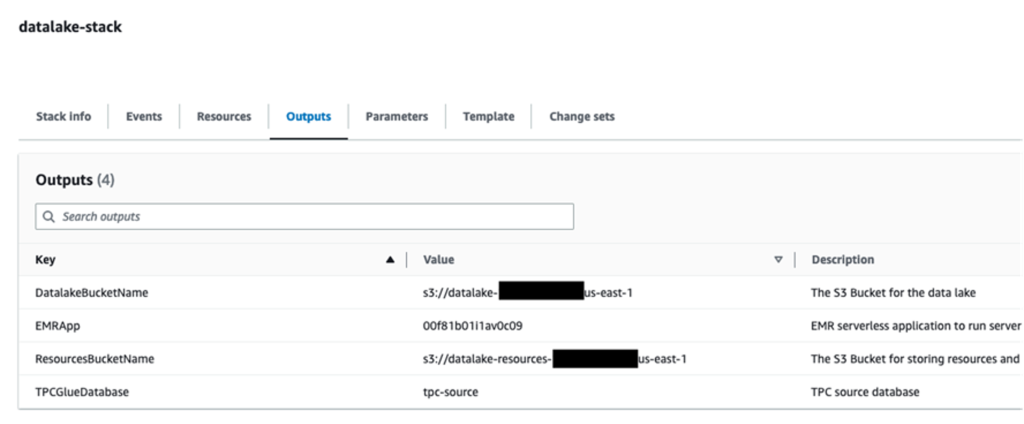
When the stack creation is complete, check the Outputs tab of the stack to verify the resources created.

Upload Spark scripts to Amazon S3

Complete the following steps to upload your Spark scripts:

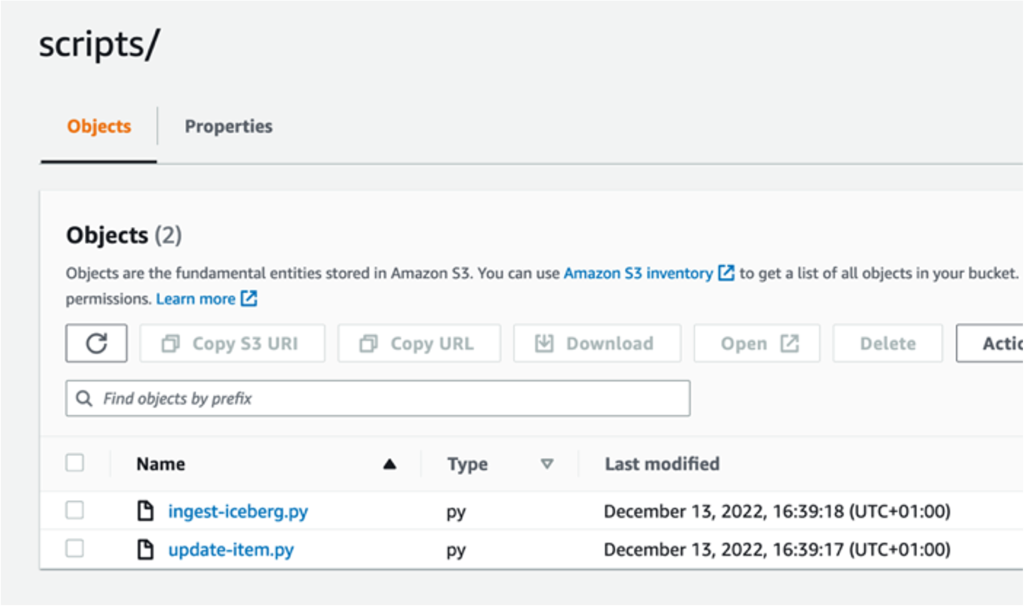
  1. Download the following scripts: ingest-iceberg.py and update-item.py.
  2. On the Amazon S3 console, go to the datalake-resources-<AccountID>-us-east-1 bucket you created earlier.
  3. Create a new folder named scripts.
  4. Upload the two PySpark scripts: ingest-iceberg.py and update-item.py.

Create Iceberg tables and ingest TPC-DS data

To create your Iceberg tables and ingest the data, complete the following steps:

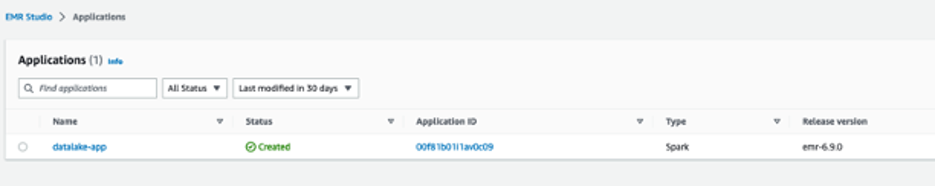
  1. On the Amazon EMR console, choose EMR Serverless in the navigation pane.
  2. Choose Manage applications.
  3. Choose the application datalake-app.

  1. Choose Start application.

Once started, it will provision the pre-initialized capacity as configured at creation (one Spark driver and two Spark executors). The pre-initialized capacity are resources that will be provisioned when you start your application. They can be used instantly when you submit jobs. However, they incur charges even if they’re not used when the application is in a started state. By default, the application is set to stop when idle for 15 minutes.

Now that the EMR application has started, we can submit the Spark ingest job ingest-iceberg.py. The job creates the Iceberg tables and then loads data from the previously created AWS Glue Data Catalog tables on TPC-DS data in an external bucket.

  1. Navigate to the datalake-app.
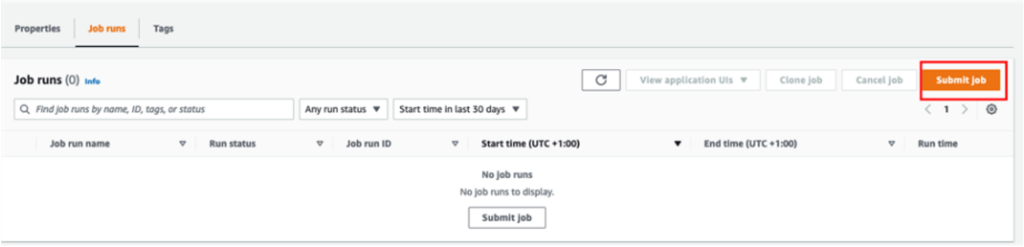
  2. On the Job runs tab, choose Submit job.

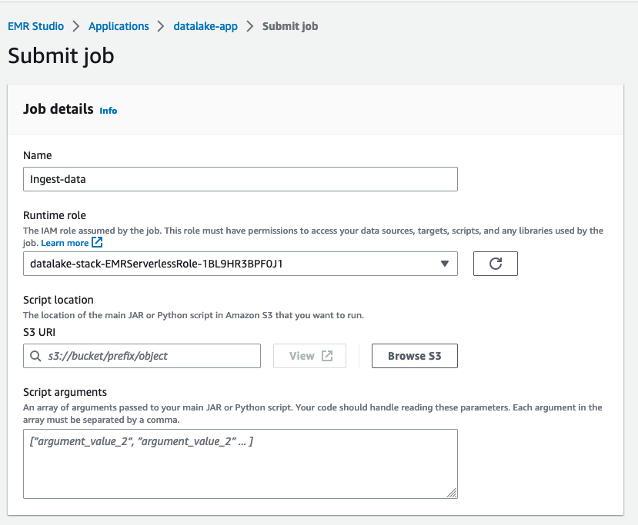
  1. For Name, enter ingest-data.
  2. For Runtime role, choose the IAM role created by the CloudFormation stack.
  3. For Script location, enter the S3 path for your resource bucket (datalake-resource-<####>-us-east-1>scripts>ingest-iceberg.py).

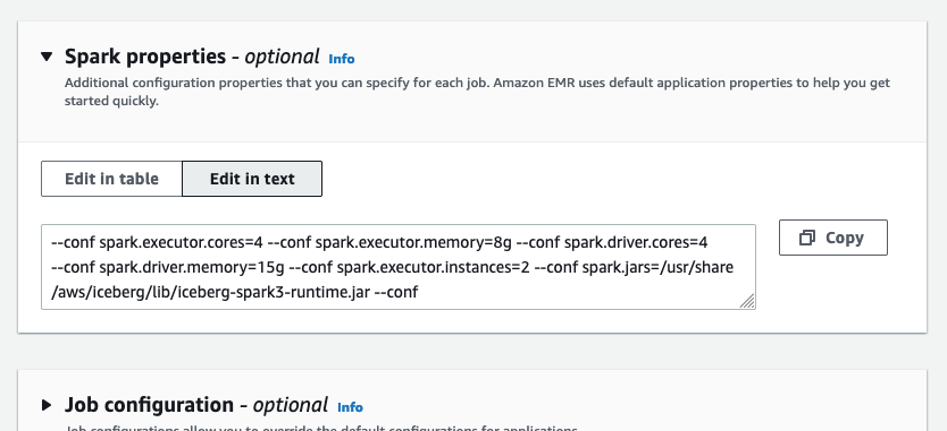
  1. Under Spark properties, choose Edit in text.
  2. Enter the following properties, replacing <BUCKET_NAME> with your data lake bucket name datalake-<####>-us-east-1 (not datalake-resources)
--conf spark.executor.cores=2 --conf spark.executor.memory=4g --conf spark.driver.cores=2 --conf spark.driver.memory=8g --conf spark.executor.instances=2 --conf spark.jars=/usr/share/aws/iceberg/lib/iceberg-spark3-runtime.jar --conf spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions --conf spark.sql.catalog.dev.warehouse=s3://<BUCKET_NAME>/warehouse --conf spark.sql.catalog.dev=org.apache.iceberg.spark.SparkCatalog --conf spark.sql.catalog.dev.catalog-impl=org.apache.iceberg.aws.glue.GlueCatalog --conf spark.sql.catalog.glue_catalog.lock-impl=org.apache.iceberg.aws.glue.DynamoLockManager --conf spark.sql.catalog.glue_catalog.lock.table=myIcebergLockTab --conf spark.dynamicAllocation.maxExecutors=8 --conf spark.driver.maxResultSize=1G --conf spark.hadoop.hive.metastore.client.factory.class=com.amazonaws.glue.catalog.metastore.AWSGlueDataCatalogHiveClientFactory

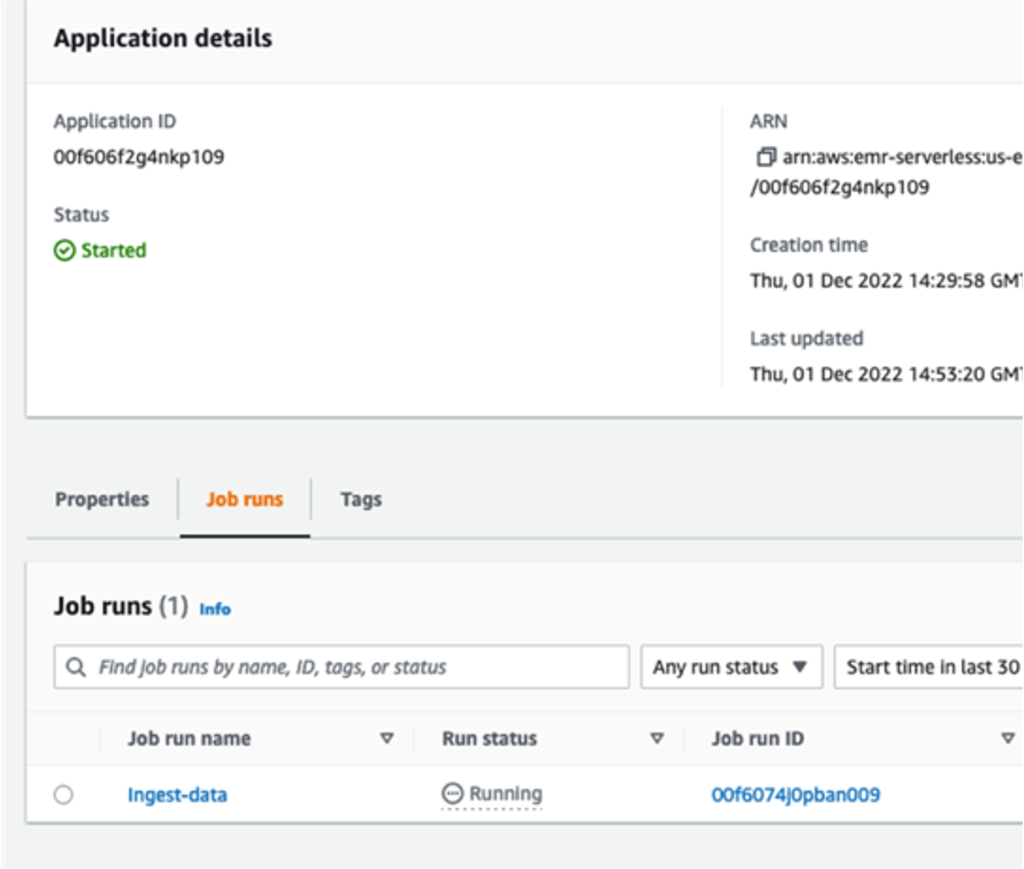
  1. Submit the job.

You can monitor the job progress.

Query Iceberg tables

In this section, we provide examples of data warehouse queries from TPC-DS on the Iceberg tables.

  1. On the Athena console, open the query editor.
  2. For Workgroup, switch to DatalakeWorkgroup.

  1. Choose Acknowledge.

The queries in DatalakeWorkgroup will run on Athena engine version 3.

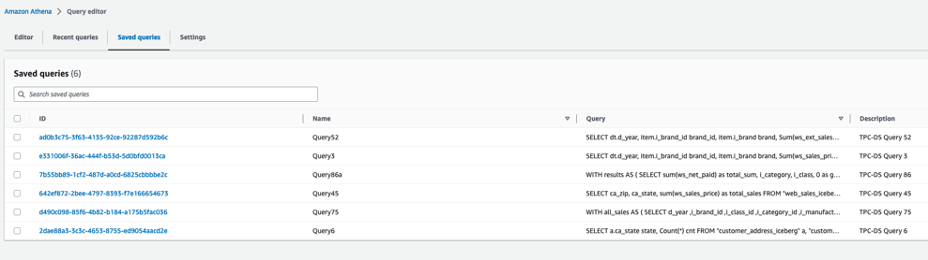
  1. On the Saved queries tab, choose a query to run on your Iceberg tables.

The following queries are listed:

  • Query3 – Report the total extended sales price per item brand of a specific manufacturer for all sales in a specific month of the year.
  • Query45 – Report the total web sales for customers in specific zip codes, cities, counties, or states, or specific items for a given year and quarter.
  • Query52 – Report the total of extended sales price for all items of a specific brand in a specific year and month.
  • Query6 – List all the states with at least 10 customers who during a given month bought items with the price tag at least 20% higher than the average price of items in the same category.
  • Query75 – For 2 consecutive years, track the sales of items by brand, class, and category.
  • Query86a – Roll up the web sales for a given year by category and class, and rank the sales among peers within the parent. For each group, compute the sum of sales and location with the hierarchy and rank within the group.

These queries are examples of queries used in decision-making and reporting in an organization. You can run them in the order you want. For this post, we start with Query3.

  1. Before you run the query, confirm that Database is set to datalake.

  1. Now you can run the query.

  1. Repeat these steps to run the other queries.

Update the item table

After running the queries, we prepare a batch of updates and inserts of records into the item table.

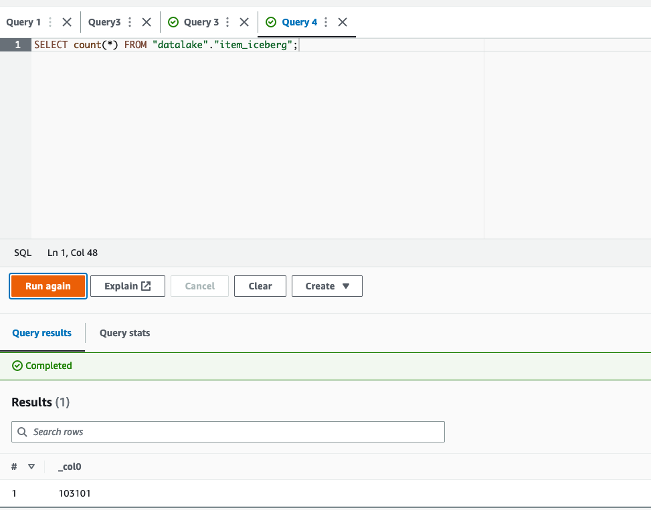
  1. First, run the following query to count the number of records in the item Iceberg table:
SELECT count(*) FROM "datalake"."item_iceberg";

This should return 102,000 records.

  1. Select item records with a price higher than $90:
SELECT count(*) FROM "datalake"."item_iceberg" WHERE i_current_price > 90.0;

This will return 1,112 records.

The update-item.py job takes these 1,112 records, modifies 11 records to change the name of the brand to Unknown, and changes the remaining 1,101 records’ i_item_id key to flag them as new records. As a result, a batch of 11 updates and 1,101 inserts are merged into the item_iceberg table.

The 11 records to be updated are those with price higher than $90, and the brand name starts with corpnameless.

  1. Run the following query:
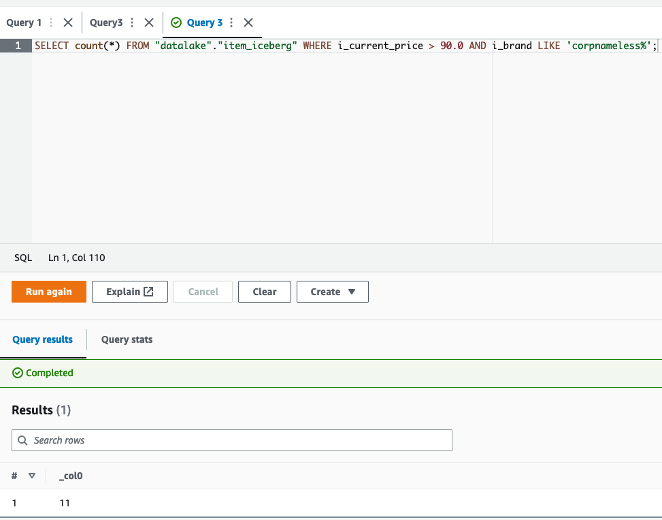
SELECT count(*) FROM "datalake"."item_iceberg" WHERE i_current_price > 90.0 AND i_brand LIKE 'corpnameless%';

The result is 11 records. The item_update.py job replaces the brand name with Unknown and merges the batch into the Iceberg table.

Now you can return to the EMR Serverless console and run the job on the EMR Serverless application.

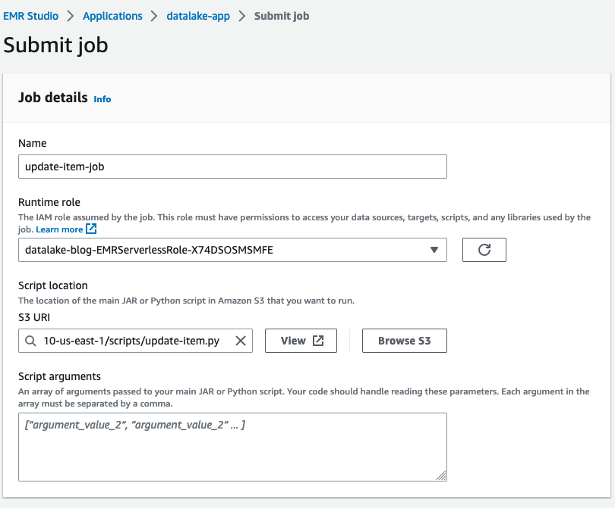
  1. On the application details page, choose Submit job.
  2. For Name, enter update-item-job.
  3. For Runtime role¸ use the same role that you used previously.
  4. For S3 URI, enter the update-item.py script location.

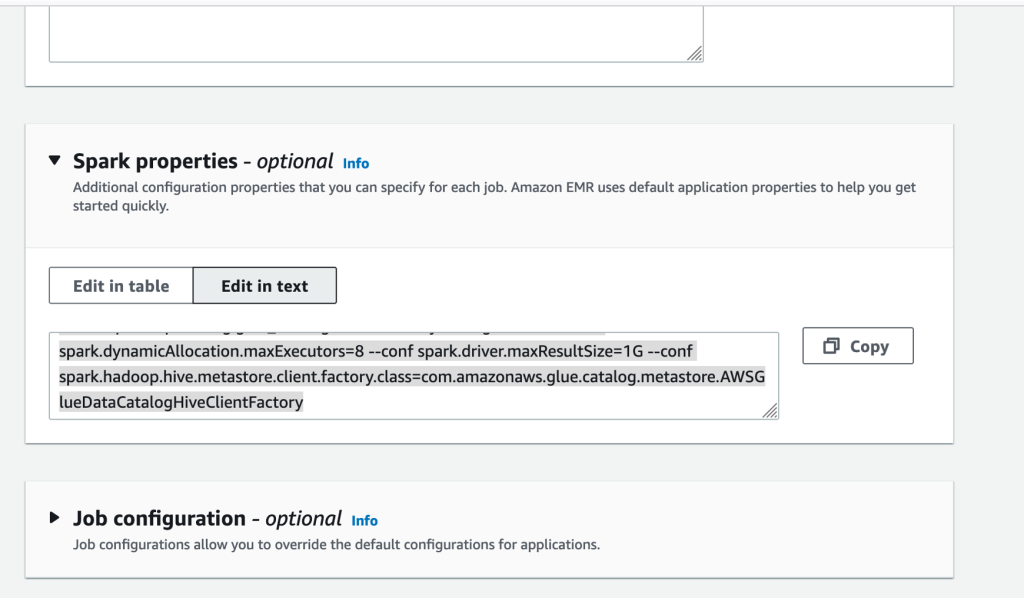
  1. Under Spark properties, choose Edit in text.
  2. Enter the following properties, replacing the <BUCKET-NAME> with your own datalake-<####>-us-east-1:
--conf spark.executor.cores=2 --conf spark.executor.memory=8g --conf spark.driver.cores=4 --conf spark.driver.memory=8g --conf spark.executor.instances=2 --conf spark.jars=/usr/share/aws/iceberg/lib/iceberg-spark3-runtime.jar --conf spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions --conf spark.sql.catalog.dev=org.apache.iceberg.spark.SparkCatalog --conf spark.sql.catalog.dev.catalog-impl=org.apache.iceberg.aws.glue.GlueCatalog --conf spark.sql.catalog.glue_catalog.lock-impl=org.apache.iceberg.aws.glue.DynamoLockManager --conf spark.sql.catalog.glue_catalog.lock.table=myIcebergLockTab --conf spark.dynamicAllocation.maxExecutors=4 --conf spark.driver.maxResultSize=1G --conf spark.sql.catalog.dev.warehouse=s3://<BUCKET-NAME>/warehouse --conf spark.hadoop.hive.metastore.client.factory.class=com.amazonaws.glue.catalog.metastore.AWSGlueDataCatalogHiveClientFactory

  1. Then submit the job.

  1. After the job finishes successfully, return to the Athena console and run the following query:
SELECT count(*) FROM "datalake"."item_iceberg";

The returned result is 103,101 = 102,000 + (1,112 – 11). The batch was merged successfully.

Time travel

To run a time travel query, complete the following steps:

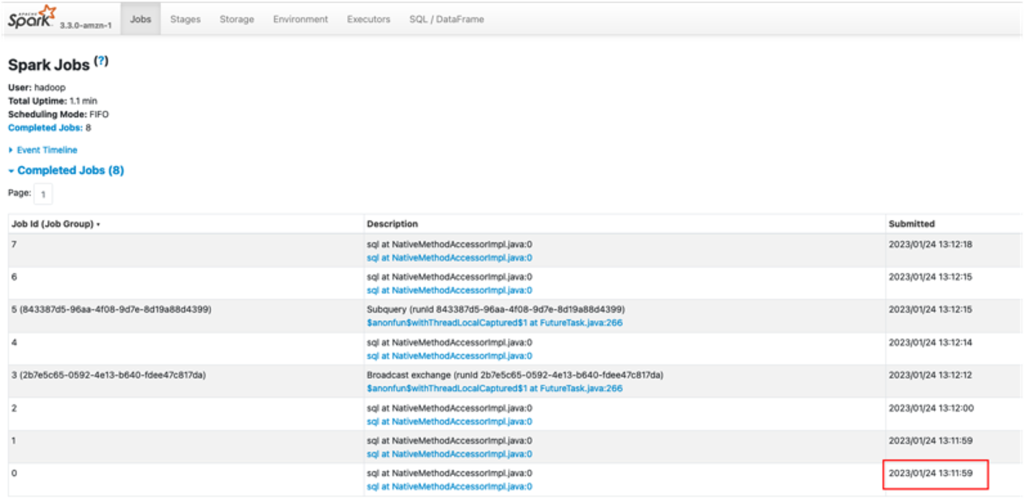
  1. Get the timestamp of the job run via the application details page on the EMR Serverless console, or the Spark UI on the History Server, as shown in the following screenshot.

This time could be just minutes before you ran the update Spark job.

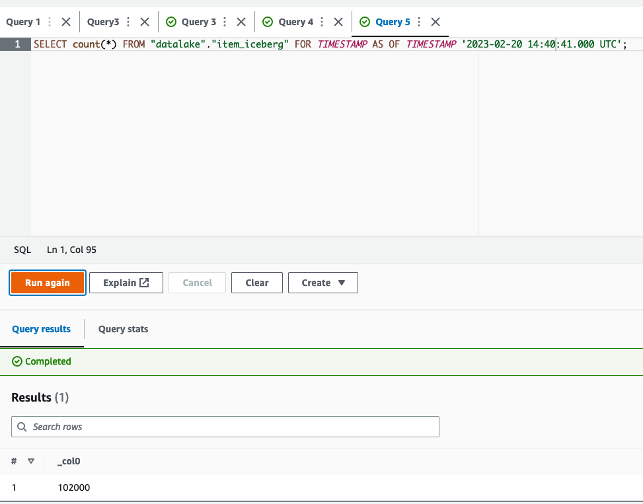
  1. Convert the timestamp from the format YYYY/MM/DD hh:mm:ss to YYYY-MM-DDThh:mm:ss.sTZD with time zone. For example, from 2023/02/20 14:40:41 to 2023-02-20 14:40:41.000 UTC.
  2. On the Athena console, run the following query to count the item table records at a time before the update job, replacing <TRAVEL_TIME> with your time:
SELECT count(*) FROM "datalake"."item_iceberg" FOR TIMESTAMP AS OF TIMESTAMP <TRAVEL_TIME>;

The query will give 102,000 as a result, the expected table size before running the update job.

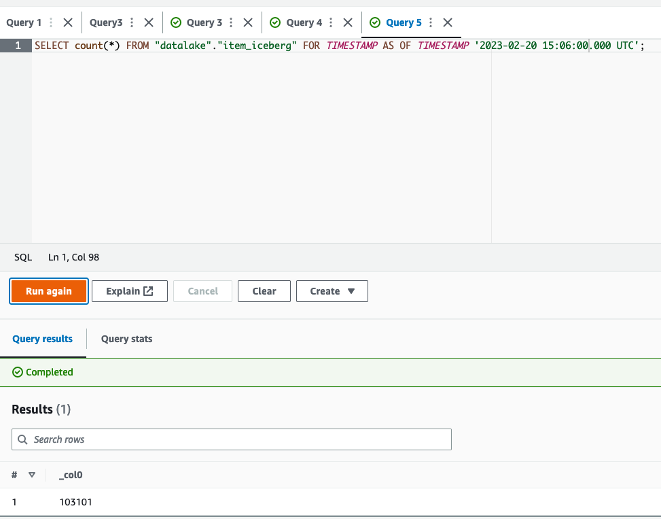
  1. Now you can run a query with a timestamp after the successful run of the update job (for example, 2023-02-20 15:06:00.000 UTC):
SELECT count(*) FROM "datalake"."item_iceberg" FOR TIMESTAMP AS OF TIMESTAMP <TRAVEL_TIME>;

The query will now give 103,101 as the size of the table at that time, after the update job successfully finished.

Additionally, you can query in Athena based on the version ID of a snapshot in Iceberg. However, for more advanced use cases, such as to roll back to a given version or to find version IDs, you can use Iceberg’s SDK or Spark on Amazon EMR.

Clean up

Complete the following steps to clean up your resources:

  1. On the Amazon S3 console, empty your buckets.
  2. On the Athena console, delete the workgroup DatalakeWorkgroup.
  3. On the EMR Studio console, stop the application datalake-app.
  4. On the AWS CloudFormation console, delete the CloudFormation stack.

Conclusion

In this post, we created a serverless transactional data lake with Iceberg tables, EMR Serverless, and Athena. We used TPC-DS sales data with 10 GB data and more than 7 million records in the fact table. We demonstrated how straightforward it is to rely on SQL and Spark to run serverless jobs for data ingestion and upserts. Moreover, we showed how to run complex BI queries directly on Iceberg tables from Athena for reporting.

You can start building your serverless transactional data lake on AWS today, and dive deep into the features and optimizations Iceberg provides to build analytics applications more easily. Iceberg can also help you in the future to improve performance and reduce costs.


About the Author

Houssem is a Specialist Solutions Architect at AWS with a focus on analytics. He is passionate about data and emerging technologies in analytics. He holds a PhD on data management in the cloud. Prior to joining AWS, he worked on several big data projects and published several research papers in international conferences and venues.

Simplify data loading into Type 2 slowly changing dimensions in Amazon Redshift

Post Syndicated from Vaidy Kalpathy original https://aws.amazon.com/blogs/big-data/simplify-data-loading-into-type-2-slowly-changing-dimensions-in-amazon-redshift/

Thousands of customers rely on Amazon Redshift to build data warehouses to accelerate time to insights with fast, simple, and secure analytics at scale and analyze data from terabytes to petabytes by running complex analytical queries. Organizations create data marts, which are subsets of the data warehouse and usually oriented for gaining analytical insights specific to a business unit or team. The star schema is a popular data model for building data marts.

In this post, we show how to simplify data loading into a Type 2 slowly changing dimension in Amazon Redshift.

Star schema and slowly changing dimension overview

A star schema is the simplest type of dimensional model, in which the center of the star can have one fact table and a number of associated dimension tables. A dimension is a structure that captures reference data along with associated hierarchies, while a fact table captures different values and metrics that can be aggregated by dimensions. Dimensions provide answers to exploratory business questions by allowing end-users to slice and dice data in a variety of ways using familiar SQL commands.

Whereas operational source systems contain only the latest version of master data, the star schema enables time travel queries to reproduce dimension attribute values on past dates when the fact transaction or event actually happened. The star schema data model allows analytical users to query historical data tying metrics to corresponding dimensional attribute values over time. Time travel is possible because dimension tables contain the exact version of the associated attributes at different time ranges. Relative to the metrics data that keeps changing on a daily or even hourly basis, the dimension attributes change less frequently. Therefore, dimensions in a star schema that keeps track of changes over time are referred to as slowly changing dimensions (SCDs).

Data loading is one of the key aspects of maintaining a data warehouse. In a star schema data model, the central fact table is dependent on the surrounding dimension tables. This is captured in the form of primary key-foreign key relationships, where the dimension table primary keys are referred by foreign keys in the fact table. In the case of Amazon Redshift, uniqueness, primary key, and foreign key constraints are not enforced. However, declaring them will help the optimizer arrive at optimal query plans, provided that the data loading processes enforce their integrity. As part of data loading, the dimension tables, including SCD tables, get loaded first, followed by the fact tables.

SCD population challenge

Populating an SCD dimension table involves merging data from multiple source tables, which are usually normalized. SCD tables contain a pair of date columns (effective and expiry dates) that represent the record’s validity date range. Changes are inserted as new active records effective from the date of data loading, while simultaneously expiring the current active record on a previous day. During each data load, incoming change records are matched against existing active records, comparing each attribute value to determine whether existing records have changed or were deleted or are new records coming in.

In this post, we demonstrate how to simplify data loading into a dimension table with the following methods:

  • Using Amazon Simple Storage Service (Amazon S3) to host the initial and incremental data files from source system tables
  • Accessing S3 objects using Amazon Redshift Spectrum to carry out data processing to load native tables within Amazon Redshift
  • Creating views with window functions to replicate the source system version of each table within Amazon Redshift
  • Joining source table views to project attributes matching with dimension table schema
  • Applying incremental data to the dimension table, bringing it up to date with source-side changes

Solution overview

In a real-world scenario, records from source system tables are ingested on a periodic basis to an Amazon S3 location before being loaded into star schema tables in Amazon Redshift.

For this demonstration, data from two source tables, customer_master and customer_address, are combined to populate the target dimension table dim_customer, which is the customer dimension table.

The source tables customer_master and customer_address share the same primary key, customer_id, and will be joined on the same to fetch one record per customer_id along with attributes from both tables. row_audit_ts contains the latest timestamp at which the particular source record was inserted or last updated. This column helps identify the change records since the last data extraction.

rec_source_status is an optional column that indicates if the corresponding source record was inserted, updated, or deleted. This is applicable in cases where the source system itself provides the changes and populates rec_source_status appropriately.

The following figure provides the schema of the source and target tables.

Let’s look closer at the schema of the target table, dim_customer. It contains different categories of columns:

  • Keys – It contains two types of keys:
    • customer_sk is the primary key of this table. It is also called the surrogate key and has a unique value that is monotonically increasing.
    • customer_id is the source primary key and provides a reference back to the source system record.
  • SCD2 metadata – rec_eff_dt and rec_exp_dt indicate the state of the record. These two columns together define the validity of the record. The value in rec_exp_dt will be set as ‘9999-12-31’ for presently active records.
  • Attributes – Includes first_name, last_name, employer_name, email_id, city, and country.

Data loading into a SCD table involves a first-time bulk data loading, referred to as the initial data load. This is followed by continuous or regular data loading, referred to as an incremental data load, to keep the records up to date with changes in the source tables.

To demonstrate the solution, we walk through the following steps for initial data load (1–7) and incremental data load (8–12):

  1. Land the source data files in an Amazon S3 location, using one subfolder per source table.
  2. Use an AWS Glue crawler to parse the data files and register tables in the AWS Glue Data Catalog.
  3. Create an external schema in Amazon Redshift to point to the AWS Glue database containing these tables.
  4. In Amazon Redshift, create one view per source table to fetch the latest version of the record for each primary key (customer_id) value.
  5. Create the dim_customer table in Amazon Redshift, which contains attributes from all relevant source tables.
  6. Create a view in Amazon Redshift joining the source table views from Step 4 to project the attributes modeled in the dimension table.
  7. Populate the initial data from the view created in Step 6 into the dim_customer table, generating customer_sk.
  8. Land the incremental data files for each source table in their respective Amazon S3 location.
  9. In Amazon Redshift, create a temporary table to accommodate the change-only records.
  10. Join the view from Step 6 and dim_customer and identify change records comparing the combined hash value of attributes. Populate the change records into the temporary table with an I, U, or D indicator.
  11. Update rec_exp_dt in dim_customer for all U and D records from the temporary table.
  12. Insert records into dim_customer, querying all I and U records from the temporary table.

Prerequisites

Before you get started, make sure you meet the following prerequisites:

Land data from source tables

Create separate subfolders for each source table in an S3 bucket and place the initial data files within the respective subfolder. In the following image, the initial data files for customer_master and customer_address are made available within two different subfolders. To try out the solution, you can use customer_master_with_ts.csv and customer_address_with_ts.csv as initial data files.

It’s important to include an audit timestamp (row_audit_ts) column that indicates when each record was inserted or last updated. As part of incremental data loading, rows with the same primary key value (customer_id) can arrive more than once. The row_audit_ts column helps identify the latest version of such records for a given customer_id to be used for further processing.

Register source tables in the AWS Glue Data Catalog

We use an AWS Glue crawler to infer metadata from delimited data files like the CSV files used in this post. For instructions on getting started with an AWS Glue crawler, refer to Tutorial: Adding an AWS Glue crawler.

Create an AWS Glue crawler and point it to the Amazon S3 location that contains the source table subfolders, within which the associated data files are placed. When you’re creating the AWS Glue crawler, create a new database named rs-dimension-blog. The following screenshots show the AWS Glue crawler configuration chosen for our data files.

Note that for the Set output and scheduling section, the advanced options are left unchanged.

Running this crawler should create the following tables within the rs-dimension-blog database:

  • customer_address
  • customer_master

Create schemas in Amazon Redshift

First, create an AWS Identity and Access Management (IAM) role named rs-dim-blog-spectrum-role. For instructions, refer to Create an IAM role for Amazon Redshift.

The IAM role has Amazon Redshift as the trusted entity, and the permissions policy includes AmazonS3ReadOnlyAccess and AWSGlueConsoleFullAccess, because we’re using the AWS Glue Data Catalog. Then associate the IAM role with the Amazon Redshift cluster or endpoint.

Instead, you can also set the IAM role as the default for your Amazon Redshift cluster or endpoint. If you do so, in the following create external schema command, pass the iam_role parameter as iam_role default.

Now, open Amazon Redshift Query Editor V2 and create an external schema passing the newly created IAM role and specifying the database as rs-dimension-blog. The database name rs-dimension-blog is the one created in the Data Catalog as part of configuring the crawler in the preceding section. See the following code:

create external schema spectrum_dim_blog 
from data catalog 
database 'rs-dimension-blog' 
iam_role 'arn:aws:iam::<accountid>:role/rs-dim-blog-spectrum-role';

Check if the tables registered in the Data Catalog in the preceding section are visible from within Amazon Redshift:

select * 
from spectrum_dim_blog.customer_master 
limit 10;

select * 
from spectrum_dim_blog.customer_address 
limit 10;

Each of these queries will return 10 rows from the respective Data Catalog tables.

Create another schema in Amazon Redshift to host the table, dim_customer:

create schema rs_dim_blog;

Create views to fetch the latest records from each source table

Create a view for the customer_master table, naming it vw_cust_mstr_latest:

create view rs_dim_blog.vw_cust_mstr_latest as with rows_numbered as (
  select 
    customer_id, 
    first_name, 
    last_name, 
    employer_name, 
    row_audit_ts, 
    row_number() over(
      partition by customer_id 
      order by 
        row_audit_ts desc
    ) as rnum 
  from 
    spectrum_dim_blog.customer_master
) 
select 
  customer_id, 
  first_name, 
  last_name, 
  employer_name, 
  row_audit_ts, 
  rnum 
from 
  rows_numbered 
where 
  rnum = 1 with no schema binding;

The preceding query uses row_number, which is a window function provided by Amazon Redshift. Using window functions enables you to create analytic business queries more efficiently. Window functions operate on a partition of a result set, and return a value for every row in that window. The row_number window function determines the ordinal number of the current row within a group of rows, counting from 1, based on the ORDER BY expression in the OVER clause. By including the PARTITION BY clause as customer_id, groups are created for each value of customer_id and ordinal numbers are reset for each group.

Create a view for the customer_address table, naming it vw_cust_addr_latest:

create view rs_dim_blog.vw_cust_addr_latest as with rows_numbered as (
  select 
    customer_id, 
    email_id, 
    city, 
    country, 
    row_audit_ts, 
    row_number() over(
      partition by customer_id 
      order by 
        row_audit_ts desc
    ) as rnum 
  from 
    spectrum_dim_blog.customer_address
) 
select 
  customer_id, 
  email_id, 
  city, 
  country, 
  row_audit_ts, 
  rnum 
from 
  rows_numbered 
where 
  rnum = 1 with no schema binding;

Both view definitions use the row_number window function of Amazon Redshift, ordering the records by descending order of the row_audit_ts column (the audit timestamp column). The condition rnum=1 fetches the latest record for each customer_id value.

Create the dim_customer table in Amazon Redshift

Create dim_customer as an internal table in Amazon Redshift within the rs_dim_blog schema. The dimension table includes the column customer_sk, that acts as the surrogate key column and enables us to capture a time-sensitive version of each customer record. The validity period for each record is defined by the columns rec_eff_dt and rec_exp_dt, representing record effective date and record expiry date, respectively. See the following code:

create table rs_dim_blog.dim_customer (
  customer_sk bigint, 
  customer_id bigint, 
  first_name varchar(100), 
  last_name varchar(100), 
  employer_name varchar(100), 
  email_id varchar(100), 
  city varchar(100), 
  country varchar(100), 
  rec_eff_dt date, 
  rec_exp_dt date
) diststyle auto;

Create a view to consolidate the latest version of source records

Create the view vw_dim_customer_src, which consolidates the latest records from both source tables using left outer join, keeping them ready to be populated into the Amazon Redshift dimension table. This view fetches data from the latest views defined in the section “Create views to fetch the latest records from each source table”:

create view rs_dim_blog.vw_dim_customer_src as 
select 
  m.customer_id, 
  m.first_name, 
  m.last_name, 
  m.employer_name, 
  a.email_id, 
  a.city, 
  a.country 
from 
  rs_dim_blog.vw_cust_mstr_latest as m 
  left join rs_dim_blog.vw_cust_addr_latest as a on m.customer_id = a.customer_id 
order by 
  m.customer_id with no schema binding;

At this point, this view fetches the initial data for loading into the dim_customer table that we are about to create. In your use-case, use a similar approach to create and join the required source table views to populate your target dimension table.

Populate initial data into dim_customer

Populate the initial data into the dim_customer table by querying the view vw_dim_customer_src. Because this is the initial data load, running row numbers generated by the row_number window function will suffice to populate a unique value in the customer_sk column starting from 1:

insert into rs_dim_blog.dim_customer 
select 
  row_number() over() as customer_sk, 
  customer_id, 
  first_name, 
  last_name, 
  employer_name, 
  email_id, 
  city, 
  country, 
  cast('2022-07-01' as date) rec_eff_dt, 
  cast('9999-12-31' as date) rec_exp_dt 
from 
  rs_dim_blog.vw_dim_customer_src;

In this query, we have specified ’2022-07-01’ as the value in rec_eff_dt for all initial data records. For your use-case, you can modify this date value as appropriate to your situation.

The preceding steps complete the initial data loading into the dim_customer table. In the next steps, we proceed with populating incremental data.

Land ongoing change data files in Amazon S3

After the initial load, the source systems provide data files on an ongoing basis, either containing only new and change records or a full extract containing all records for a particular table.

You can use the sample files customer_master_with_ts_incr.csv and customer_address_with_ts_incr.csv, which contain changed as well as new records. These incremental files need to be placed in the same location in Amazon S3 where the initial data files were placed. Please see section “Land data from source tables”. This will result in the corresponding Redshift Spectrum tables automatically reading the additional rows.

If you used the sample file for customer_master, after adding the incremental files, the following query shows the initial as well as incremental records:

select 
  customer_id, 
  first_name, 
  last_name, 
  employer_name, 
  row_audit_ts 
from 
  spectrum_dim_blog.customer_master 
order by 
  customer_id;

In case of full extracts, we can identify deletes occurring in the source system tables by comparing the previous and current versions and looking for missing records. In case of change-only extracts where the rec_source_status column is present, its value will help us identify deleted records. In either case, land the ongoing change data files in the respective Amazon S3 locations.

For this example, we have uploaded the incremental data for the customer_master and customer_address source tables with a few customer_id records receiving updates and a few new records being added.

Create a temporary table to capture change records

Create the temporary table temp_dim_customer to store all changes that need to be applied to the target dim_customer table:

create temp table temp_dim_customer (
  customer_sk bigint, 
  customer_id bigint, 
  first_name varchar(100), 
  last_name varchar(100), 
  employer_name varchar(100), 
  email_id varchar(100), 
  city varchar(100), 
  country varchar(100), 
  rec_eff_dt date, 
  rec_exp_dt date, 
  iud_operation character(1)
);

Populate the temporary table with new and changed records

This is a multi-step process that can be combined into a single complex SQL. Complete the following steps:

  1. Fetch the latest version of all customer attributes by querying the view vw_dim_customer_src:
select 
  customer_id, 
  sha2(
    coalesce(first_name, '') || coalesce(last_name, '') || coalesce(employer_name, '') || coalesce(email_id, '') || coalesce(city, '') || coalesce(country, ''), 512
  ) as hash_value, 
  first_name, 
  last_name, 
  employer_name, 
  email_id, 
  city, 
  country, 
  current_date rec_eff_dt, 
  cast('9999-12-31' as date) rec_exp_dt 
from 
  rs_dim_blog.vw_dim_customer_src;

Amazon Redshift offers hashing functions such as sha2, which converts a variable length string input into a fixed length character output. The output string is a text representation of the hexadecimal value of the checksum with the specified number of bits. In this case, we pass a concatenated set of customer attributes whose change we want to track, specifying the number of bits as 512. We’ll use the output of the hash function to determine if any of the attributes have undergone a change. This dataset will be called newver (new version).

Because we landed the ongoing change data in the same location as the initial data files, the records retrieved from the preceding query (in newver) include all records, even the unchanged ones. But because of the definition of the view vw_dim_customer_src, we get only one record per customerid, which is its latest version based on row_audit_ts.

  1. In a similar manner, retrieve the latest version of all customer records from dim_customer, which are identified by rec_exp_dt=‘9999-12-31’. While doing so, also retrieve the sha2 value of all customer attributes available in dim_customer:
select 
  customer_id, 
  sha2(
    coalesce(first_name, '') || coalesce(last_name, '') || coalesce(employer_name, '') || coalesce(email_id, '') || coalesce(city, '') || coalesce(country, ''), 512
  ) as hash_value, 
  first_name, 
  last_name, 
  employer_name, 
  email_id, 
  city, 
  country 
from 
  rs_dim_blog.dim_customer 
where 
  rec_exp_dt = '9999-12-31';

This dataset will be called oldver (old or existing version).

  1. Identify the current maximum surrogate key value from the dim_customer table:
select 
  max(customer_sk) as maxval 
from 
  rs_dim_blog.dim_customer;

This value (maxval) will be added to the row_number before being used as the customer_sk value for the change records that need to be inserted.

  1. Perform a full outer join of the old version of records (oldver) and the new version (newver) of records on the customer_id column. Then compare the old and new hash values generated by the sha2 function to determine if the change record is an insert, update, or delete:
case when oldver.customer_id is null then 'I'
when newver.customer_id is null then 'D'
when oldver.hash_value != newver.hash_value then 'U'
else 'N' end as iud_op

We tag the records as follows:

  • If the customer_id is non-existent in the oldver dataset (oldver.customer_id is null), it’s tagged as an insert (‘I').
  • Otherwise, if the customer_id is non-existent in the newver dataset (newver.customer_id is null), it’s tagged as a delete (‘D').
  • Otherwise, if the old hash_value and new hash_value are different, these records represent an update (‘U').
  • Otherwise, it indicates that the record has not undergone any change and therefore can be ignored or marked as not-to-be-processed (‘N').

Make sure to modify the preceding logic if the source extract contains rec_source_status to identify deleted records.

Although sha2 output maps a possibly infinite set of input strings to a finite set of output strings, the chances of collision of hash values for the original row values and changed row values are very unlikely. Instead of individually comparing each column value before and after, we compare the hash values generated by sha2 to conclude if there has been a change in any of the attributes of the customer record. For your use-case, we recommend you choose a hash function that works for your data conditions after adequate testing. Instead, you can compare individual column values if none of the hash functions satisfactorily meet your expectations.

  1. Combining the outputs from the preceding steps, let’s create the INSERT statement that captures only change records to populate the temporary table:
insert into temp_dim_customer (
  customer_sk, customer_id, first_name, 
  last_name, employer_name, email_id, 
  city, country, rec_eff_dt, rec_exp_dt, 
  iud_operation
) with newver as (
  select 
    customer_id, 
    sha2(
      coalesce(first_name, '') || coalesce(last_name, '') || coalesce(employer_name, '') || coalesce(email_id, '') || coalesce(city, '') || coalesce(country, ''), 512
    ) as hash_value, 
    first_name, 
    last_name, 
    employer_name, 
    email_id, 
    city, 
    country, 
    current_date rec_eff_dt, 
    cast('9999-12-31' as date) rec_exp_dt 
  from 
    rs_dim_blog.vw_dim_customer_src
), 
oldver as (
  select 
    customer_id, 
    sha2(
      coalesce(first_name, '') || coalesce(last_name, '') || coalesce(employer_name, '') || coalesce(email_id, '') || coalesce(city, '') || coalesce(country, ''), 512
    ) as hash_value, 
    first_name, 
    last_name, 
    employer_name, 
    email_id, 
    city, 
    country 
  from 
    rs_dim_blog.dim_customer 
  where 
    rec_exp_dt = '9999-12-31'
), 
maxsk as (
  select 
    max(customer_sk) as maxval 
  from 
    rs_dim_blog.dim_customer
), 
allrecs as (
  select 
    coalesce(oldver.customer_id, newver.customer_id) as customer_id, 
    case when oldver.customer_id is null then 'I' when newver.customer_id is null then 'D' when oldver.hash_value != newver.hash_value then 'U' else 'N' end as iud_op, 
    newver.first_name, 
    newver.last_name, 
    newver.employer_name, 
    newver.email_id, 
    newver.city, 
    newver.country, 
    newver.rec_eff_dt, 
    newver.rec_exp_dt 
  from 
    oldver full 
    outer join newver on oldver.customer_id = newver.customer_id
) 
select 
  (maxval + (row_number() over())) as customer_sk, 
  customer_id, 
  first_name, 
  last_name, 
  employer_name, 
  email_id, 
  city, 
  country, 
  rec_eff_dt, 
  rec_exp_dt, 
  iud_op 
from 
  allrecs, 
  maxsk 
where 
  iud_op != 'N';

Expire updated customer records

With the temp_dim_customer table now containing only the change records (either ‘I’, ‘U’, or ‘D’), the same can be applied on the target dim_customer table.

Let’s first fetch all records with values ‘U’ or ‘D’ in the iud_op column. These are records that have either been deleted or updated in the source system. Because dim_customer is a slowly changing dimension, it needs to reflect the validity period of each customer record. In this case, we expire the presently active recorts that have been updated or deleted. We expire these records as of yesterday (by setting rec_exp_dt=current_date-1) matching on the customer_id column:

update 
  rs_dim_blog.dim_customer 
set 
  rec_exp_dt = current_date - 1 
where 
  customer_id in (
    select 
      customer_id 
    from 
      temp_dim_customer as t 
    where 
      iud_operation in ('U', 'D')
  ) 
  and rec_exp_dt = '9999-12-31';

Insert new and changed records

As the last step, we need to insert the newer version of updated records along with all first-time inserts. These are indicated by ‘U’ and ‘I’, respectively, in the iud_op column in the temp_dim_customer table:

insert into rs_dim_blog.dim_customer (
  customer_sk, customer_id, first_name, 
  last_name, employer_name, email_id, 
  city, country, rec_eff_dt, rec_exp_dt
) 
select 
  customer_sk, 
  customer_id, 
  first_name, 
  last_name, 
  employer_name, 
  email_id, 
  city, 
  country, 
  rec_eff_dt, 
  rec_exp_dt 
from 
  temp_dim_customer 
where 
  iud_operation in ('I', 'U');

Depending on the SQL client setting, you might want to run a commit transaction; command to verify that the preceding changes are persisted successfully in Amazon Redshift.

Check the final output

You can run the following query and see that the dim_customer table now contains both the initial data records plus the incremental data records, capturing multiple versions for those customer_id values that got changed as part of incremental data loading. The output also indicates that each record has been populated with appropriate values in rec_eff_dt and rec_exp_dt corresponding to the record validity period.

select 
  * 
from 
  rs_dim_blog.dim_customer 
order by 
  customer_id, 
  customer_sk;

For the sample data files provided in this article, the preceding query returns the following records. If you’re using the sample data files provided in this post, note that the values in customer_sk may not match with what is shown in the following table.

In this post, we only show the important SQL statements; the complete SQL code is available in load_scd2_sample_dim_customer.sql.

Clean up

If you no longer need the resources you created, you can delete them to prevent incurring additional charges.

Conclusion

In this post, you learned how to simplify data loading into Type-2 SCD tables in Amazon Redshift, covering both initial data loading and incremental data loading. The approach deals with multiple source tables populating a target dimension table, capturing the latest version of source records as of each run.

Refer to Amazon Redshift data loading best practices for further materials and additional best practices, and see Updating and inserting new data for instructions to implement updates and inserts.


About the Author

Vaidy Kalpathy is a Senior Data Lab Solution Architect at AWS, where he helps customers modernize their data platform and defines end to end data strategy including data ingestion, transformation, security, visualization. He is passionate about working backwards from business use cases, creating scalable and custom fit architectures to help customers innovate using data analytics services on AWS.

Establishing a data perimeter on AWS: Allow only trusted resources from my organization

Post Syndicated from Laura Reith original https://aws.amazon.com/blogs/security/establishing-a-data-perimeter-on-aws-allow-only-trusted-resources-from-my-organization/

Companies that store and process data on Amazon Web Services (AWS) want to prevent transfers of that data to or from locations outside of their company’s control. This is to support security strategies, such as data loss prevention, or to comply with the terms and conditions set forth by various regulatory and privacy agreements. On AWS, a resource perimeter is a set of AWS Identity and Access Management (IAM) features and capabilities that you can use to build your defense-in-depth protection against unintended data transfers. In this third blog post of the Establishing a data perimeter on AWS series, we review the benefits and implementation considerations when you define your resource perimeter.

The resource perimeter is one of the three perimeters in the data perimeter framework on AWS and has the following two control objectives:

  • My identities can access only trusted resources – This helps to ensure that IAM principals that belong to your AWS Organizations organization can access only the resources that you trust.
  • Only trusted resources can be accessed from my network – This helps to ensure that only resources that you trust can be accessed through expected networks, regardless of the principal that is making the API call.

Trusted resources are the AWS resources, such as Amazon Simple Storage Service (Amazon S3) buckets and objects or Amazon Simple Notification Service (Amazon SNS) topics, that are owned by your organization and in which you store and process your data. Additionally, there are resources outside your organization that your identities or AWS services acting on your behalf might need to access. You will need to consider these access patterns when you define your resource perimeter.

Security risks addressed by the resource perimeter

The resource perimeter helps address three main security risks.

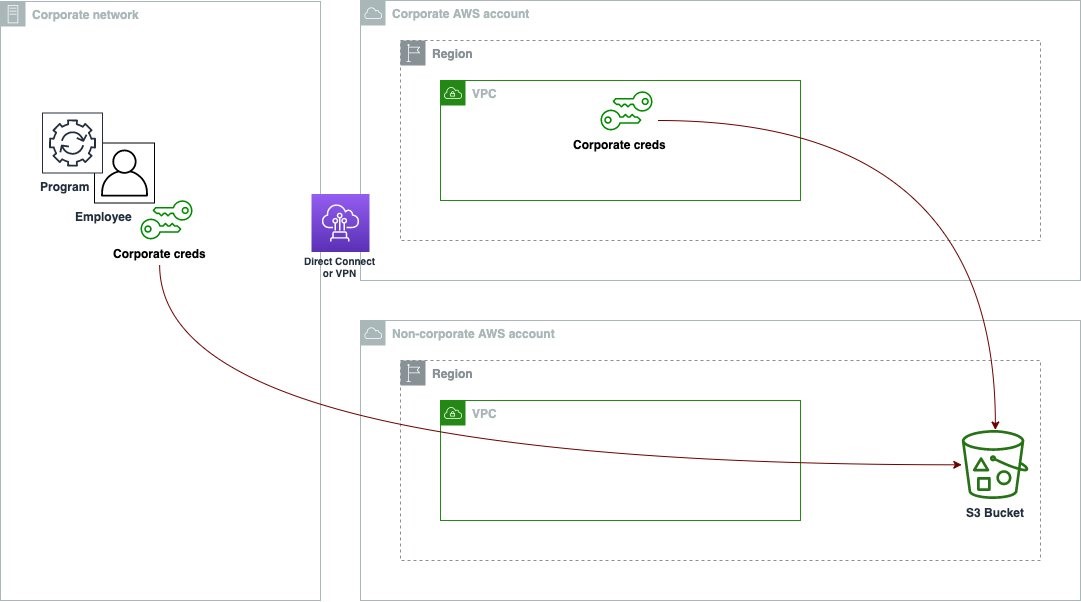
Unintended data disclosure through use of corporate credentials — Your developers might have a personal AWS account that is not part of your organization. In that account, they could configure a resource with a resource-based policy that allows their corporate credentials to interact with the resource. For example, they could write an S3 bucket policy that allows them to upload objects by using their corporate credentials. This could allow the intentional or unintentional transfer of data from your corporate environment — your on-premises network or virtual private cloud (VPC) — to their personal account. While you advance through your least privilege journey, you should make sure that access to untrusted resources is prohibited, regardless of the permissions granted by identity-based policies that are attached to your IAM principals. Figure 1 illustrates an unintended access pattern where your employee uses an identity from your organization to move data from your on-premises or AWS environment to an S3 bucket in a non-corporate AWS account.

Figure 1: Unintended data transfer to an S3 bucket outside of your organization by your identities

Figure 1: Unintended data transfer to an S3 bucket outside of your organization by your identities

Unintended data disclosure through non-corporate credentials usage — There is a risk that developers could introduce personal IAM credentials to your corporate network and attempt to move company data to personal AWS resources. We discussed this security risk in a previous blog post: Establishing a data perimeter on AWS: Allow only trusted identities to access company data. In that post, we described how to use the aws:PrincipalOrgID condition key to prevent the use of non-corporate credentials to move data into an untrusted location. In the current post, we will show you how to implement resource perimeter controls as a defense-in-depth approach to mitigate this risk.

Unintended data infiltration — There are situations where your developers might start the solution development process using commercial datasets, tooling, or software and decide to copy them from repositories, such as those hosted on public S3 buckets. This could introduce malicious components into your corporate environment, your on-premises network, or VPCs. Establishing the resource perimeter to only allow access to trusted resources from your network can help mitigate this risk. Figure 2 illustrates the access pattern where an employee with corporate credentials downloads assets from an S3 bucket outside of your organization.

Figure 2: Unintended data infiltration

Figure 2: Unintended data infiltration

Implement the resource perimeter

To achieve the resource perimeter control objectives, you can implement guardrails in your AWS environment by using the following AWS policy types:

  • Service control policies (SCPs) – Organization policies that are used to centrally manage and set the maximum available permissions for your IAM principals. SCPs help you ensure that your accounts stay within your organization’s access control guidelines. In the context of the resource perimeter, you will use SCPs to help prevent access to untrusted resources from AWS principals that belong to your organization.
  • VPC endpoint policy – An IAM resource-based policy that is attached to a VPC endpoint to control which principals, actions, and resources can be accessed through a VPC endpoint. In the context of the resource perimeter, VPC endpoint policies are used to validate that the resource the principal is trying to access belongs to your organization.

The condition key used to constrain access to resources in your organization is aws:ResourceOrgID. You can set this key in an SCP or VPC endpoint policy. The following table summarizes the relationship between the control objectives and the AWS capabilities used to implement the resource perimeter.

Control objective Implemented by using Primary IAM capability
My identities can access only trusted resources SCPs aws:ResourceOrgID
Only trusted resources can be accessed from my network VPC endpoint policies aws:ResourceOrgID

In the next section, you will learn how to use the IAM capabilities listed in the preceding table to implement each control objective of the resource perimeter.

My identities can access only trusted resources

The following is an example of an SCP that limits all actions to only the resources that belong to your organization. Replace <MY-ORG-ID> with your information.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "EnforceResourcePerimeter",
      "Effect": "Deny",
      "Action": "*",
      "Resource": "*",
      "Condition": {
        "StringNotEqualsIfExists": {
          "aws:ResourceOrgID": "<MY-ORG-ID>"
        }
      }
    }
  ]
}

In this policy, notice the use of the negated condition key StringNotEqualsIfExists. This means that this condition will evaluate to true and the policy will deny API calls if the organization identifier of the resource that is being accessed differs from the one specified in the policy. It also means that this policy will deny API calls if the resource being accessed belongs to a standalone account, which isn’t part of an organization. The negated condition operators in the Deny statement mean that the condition still evaluates to true if the key is not present in the request; however, as a best practice, I added IfExists to the end of the StringNotEquals operator to clearly express the intent in the policy.

Note that for a permission to be allowed for a specific account, a statement that allows access must exist at every level of the hierarchy of your organization.

Only trusted resources can be accessed from my network

You can achieve this objective by combining the SCP we just reviewed with the use of aws:PrincipalOrgID in your VPC endpoint policies, as shown in the Establishing a data perimeter on AWS: Allow only trusted identities to access company data blog post. However, as a defense in depth, you can also apply resource perimeter controls on your networks by using aws:ResourceOrgID in your VPC endpoint policies.

The following is an example of a VPC endpoint policy that allows access to all actions but limits access to only trusted resources and identities that belong to your organization. Replace <MY-ORG-ID> with your information.

{
	"Version": "2012-10-17",
	"Statement": [
		{
			"Sid": "AllowRequestsByOrgsIdentitiesToOrgsResources",
			"Effect": "Allow",
			"Principal": {
				"AWS": "*"
			},
			"Action": "*",
			"Resource": "*",
			"Condition": {
				"StringEquals": {
					"aws:PrincipalOrgID": "<MY-ORG-ID>",
					"aws:ResourceOrgID": "<MY-ORG-ID>"
				}
			}
		}
	]
}

The preceding VPC endpoint policy uses the StringEquals condition operator. To invoke the Allow effect, the principal making the API call and the resource they are trying to access both need to belong to your organization. Compared to the SCP example that we reviewed earlier, your intent for this policy is different — you want to make sure that the Allow condition evaluates to true only if the specified key exists in the request. Additionally, VPC endpoint policies apply to principals, as long as their request flows through the VPC endpoint.

In VPC endpoint policies, you do not grant permissions; rather, you define the maximum allowed access through the network. Therefore, this policy uses an Allow effect.

Extend your resource perimeter

The previous two policies help you ensure that your identities and networks can only be used to access AWS resources that belong to your organization. However, your company might require that you extend your resource perimeter to also include AWS owned resources — resources that do not belong to your organization and that are accessed by your principals or by AWS services acting on your behalf. For example, if you use the AWS Service Catalog in your environment, the service creates and uses Amazon S3 buckets that are owned by the service to store products. To allow your developers to successfully provision AWS Service Catalog products, your resource perimeter needs to account for this access pattern. The following statement shows how to account for the service catalog access pattern. Replace <MY-ORG-ID> with your information.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "EnforceResourcePerimeter",
      "Effect": "Deny",
      "NotAction": [
        "s3:GetObject",
        "s3:PutObject",
        "s3:PutObjectAcl"
      ],
      "Resource": "*",
      "Condition": {
        "StringNotEqualsIfExists": {
          "aws:ResourceOrgID": "<MY-ORG-ID>"
        }
      }
    },
    {
      "Sid": "ExtendResourcePerimeter",
      "Effect": "Deny",
      "Action": [
        "s3:GetObject",
        "s3:PutObject",
        "s3:PutObjectAcl"
      ],
      "Resource": [
        "*"
      ],
      "Condition": {
        "StringNotEqualsIfExists": {
          "aws:ResourceOrgID": "<MY-ORG-ID>"
        },
        "ForAllValues:StringNotEquals": {
          "aws:CalledVia": [
            "servicecatalog.amazonaws.com"
          ]
        }
      }
    }
  ]
}

Note that the EnforceResourcePerimeter statement in the SCP was modified to exclude s3:GetObject, s3:PutObject, and s3:PutObjectAcl actions from its effect (NotAction element). This is because these actions are performed by the Service Catalog to access service-owned S3 buckets. These actions are then restricted in the ExtendResourcePerimeter statement, which includes two negated condition keys. The second statement denies the previously mentioned S3 actions unless the resource that is being accessed belongs to your organization (StringNotEqualsIfExists with aws:ResourceOrgID), or the actions are performed by Service Catalog on your behalf (ForAllValues:StringNotEquals with aws:CalledVia). The aws:CalledVia condition key compares the services specified in the policy with the services that made requests on behalf of the IAM principal by using that principal’s credentials. In the case of the Service Catalog, the credentials of a principal who launches a product are used to access S3 buckets that are owned by the Service Catalog.

It is important to highlight that we are purposely not using the aws:ViaAWSService condition key in the preceding policy. This is because when you extend your resource perimeter, we recommend that you restrict access to only calls to buckets that are accessed by the service you are using.

You might also need to extend your resource perimeter to include the third-party resources of your partners. For example, you could be working with business partners that require your principals to upload or download data to or from S3 buckets that belong to their account. In this case, you can use the aws:ResourceAccount condition key in your resource perimeter policy to specify resources that belong to the trusted third-party account.

The following is an example of an SCP that accounts for access to the Service Catalog and third-party partner resources. Replace <MY-ORG-ID> and <THIRD-PARTY-ACCOUNT> with your information.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "EnforceResourcePerimeter",
      "Effect": "Deny",
      "NotAction": [
        "s3:GetObject",
        "s3:PutObject",
        "s3:PutObjectAcl"
      ],
      "Resource": "*",
      "Condition": {
        "StringNotEqualsIfExists": {
          "aws:ResourceOrgID": "<MY-ORG-ID>"
        }
      }
    },
    {
      "Sid": "ExtendResourcePerimeter",
      "Effect": "Deny",
      "Action": [
        "s3:GetObject",
        "s3:PutObject",
        "s3:PutObjectAcl"
      ],
      "Resource": [
        "*"
      ],
      "Condition": {
        "StringNotEqualsIfExists": {
          "aws:ResourceOrgID": "<MY-ORG-ID>",
          "aws:ResourceAccount": "<THIRD-PARTY-ACCOUNT>"
        },
        "ForAllValues:StringNotEquals": {
          "aws:CalledVia": [
            "servicecatalog.amazonaws.com"
          ]
        }
      }
    }
  ]
}

To account for access to trusted third-party account resources, the condition StringNotEqualsIfExists in the ExtendResourcePerimeter statement now also contains the condition key aws:ResourceAccount. Now, the second statement denies the previously mentioned S3 actions unless the resource that is being accessed belongs to your organization (StringNotEqualsIfExists with aws:ResourceOrgID), to a trusted third-party account (StringNotEqualsIfExists with aws:ResourceAccount), or the actions are performed by Service Catalog on your behalf (ForAllValues:StringNotEquals with aws:CalledVia).

The next policy example demonstrates how to extend your resource perimeter to permit access to resources that are owned by your trusted third parties through the networks that you control. This is required if applications running in your VPC or on-premises need to be able to access a dataset that is created and maintained in your business partner AWS account. Similar to the SCP example, you can use the aws:ResourceAccount condition key in your VPC endpoint policy to account for this access pattern. Replace <MY-ORG-ID>, <THIRD-PARTY-ACCOUNT>, and <THIRD-PARTY-RESOURCE-ARN> with your information.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "AllowRequestsByOrgsIdentitiesToOrgsResources",
      "Effect": "Allow",
      "Principal": {
        "AWS": "*"
      },
      "Action": "*",
      "Resource": "*",
      "Condition": {
        "StringEquals": {
          "aws:PrincipalOrgID": "<MY-ORG-ID>",
          "aws:ResourceOrgID": "<MY-ORG-ID>"
        }
      }
    },
    {
      "Sid": "AllowRequestsByOrgsIdentitiesToThirdPartyResources",
      "Effect": "Allow",
      "Principal": {
        "AWS": "*"
      },
      "Action": [
        "s3:GetObject",
        "s3:PutObject",
        "s3:PutObjectAcl"
      ],
      "Resource": [
        "<THIRD-PARTY-RESOURCE-ARN>"
      ],
      "Condition": {
        "StringEquals": {
          "aws:PrincipalOrgID": "<MY-ORG-ID>",
          "aws:ResourceAccount": [
            "<THIRD-PARTY-ACCOUNT>"
          ]
        }
      }
    }
  ]
}

The second statement, AllowRequestsByOrgsIdentitiesToThirdPartyResources, in the updated VPC endpoint policy allows s3:GetObject, s3:PutObject, and s3:PutObjectAcl actions on trusted third-party resources (StringEquals with aws:ResourceAccount) by principals that belong to your organization (StringEquals with aws:PrincipalOrgID).

Note that you do not need to modify your VPC endpoint policy to support the previously discussed Service Catalog operations. This is because calls to Amazon S3 made by Service Catalog on your behalf originate from the Service Catalog service network and do not traverse your VPC endpoint. However, you should consider access patterns that are similar to the Service Catalog example when defining your trusted resources. To learn about services with similar access patterns, see the IAM policy samples section later in this post.

Deploy the resource perimeter at scale

For recommendations on deploying a data perimeter at scale, see the Establishing a data perimeter on AWS: Allow only trusted identities to access company data blog post. The section titled Deploying the identity perimeter at scale provides the details on how to achieve this for your organization.

IAM policy samples

Our GitHub repository contains policy examples that illustrate how to implement perimeter controls for a variety of AWS services. The policy examples in the repository are for reference only. You will need to tailor them to suit the specific needs of your AWS environment.

Conclusion

In this blog post, you learned about the resource perimeter, the control objectives achieved by the perimeter, and how to write SCPs and VPC endpoint policies that help achieve these objectives for your organization. You also learned how to extend your perimeter to include AWS service-owned resources and your third-party partner-owned resources.

For additional learning opportunities, see the Data perimeters on AWS page. This information resource provides additional materials such as a data perimeter workshop, blog posts, whitepapers, and webinar sessions.

If you have questions, comments, or concerns, contact AWS Support or browse AWS re:Post. If you have feedback about this post, submit comments in the Comments section below.

Want more AWS Security news? Follow us on Twitter.

Author

Laura Reith

Laura is an Identity Solutions Architect at Amazon Web Services. Before AWS, she worked as a Solutions Architect in Taiwan focusing on physical security and retail analytics.

Tatyana Yatskevich

Tatyana Yatskevich

Tatyana is a Principal Solutions Architect in AWS Identity. She works with customers to help them build and operate in AWS in the most secure and efficient manner.

Build an end-to-end change data capture with Amazon MSK Connect and AWS Glue Schema Registry

Post Syndicated from Kalyan Janaki original https://aws.amazon.com/blogs/big-data/build-an-end-to-end-change-data-capture-with-amazon-msk-connect-and-aws-glue-schema-registry/

The value of data is time sensitive. Real-time processing makes data-driven decisions accurate and actionable in seconds or minutes instead of hours or days. Change data capture (CDC) refers to the process of identifying and capturing changes made to data in a database and then delivering those changes in real time to a downstream system. Capturing every change from transactions in a source database and moving them to the target in real time keeps the systems synchronized, and helps with real-time analytics use cases and zero-downtime database migrations. The following are a few benefits of CDC:

  • It eliminates the need for bulk load updating and inconvenient batch windows by enabling incremental loading or real-time streaming of data changes into your target repository.
  • It ensures that data in multiple systems stays in sync. This is especially important if you’re making time-sensitive decisions in a high-velocity data environment.

Kafka Connect is an open-source component of Apache Kafka that works as a centralized data hub for simple data integration between databases, key-value stores, search indexes, and file systems. The AWS Glue Schema Registry allows you to centrally discover, control, and evolve data stream schemas. Kafka Connect and Schema Registry integrate to capture schema information from connectors. Kafka Connect provides a mechanism for converting data from the internal data types used by Kafka Connect to data types represented as Avro, Protobuf, or JSON Schema. AvroConverter, ProtobufConverter, and JsonSchemaConverter automatically register schemas generated by Kafka connectors (source) that produce data to Kafka. Connectors (sink) that consume data from Kafka receive schema information in addition to the data for each message. This allows sink connectors to know the structure of the data to provide capabilities like maintaining a database table schema in a data catalog.

The post demonstrates how to build an end-to-end CDC using Amazon MSK Connect, an AWS managed service to deploy and run Kafka Connect applications and AWS Glue Schema Registry, which allows you to centrally discover, control, and evolve data stream schemas.

Solution overview

On the producer side, for this example we choose a MySQL-compatible Amazon Aurora database as the data source, and we have a Debezium MySQL connector to perform CDC. The Debezium connector continuously monitors the databases and pushes row-level changes to a Kafka topic. The connector fetches the schema from the database to serialize the records into a binary form. If the schema doesn’t already exist in the registry, the schema will be registered. If the schema exists but the serializer is using a new version, the schema registry checks the compatibility mode of the schema before updating the schema. In this solution, we use backward compatibility mode. The schema registry returns an error if a new version of the schema is not backward compatible, and we can configure Kafka Connect to send incompatible messages to the dead-letter queue.

On the consumer side, we use an Amazon Simple Storage Service (Amazon S3) sink connector to deserialize the record and store changes to Amazon S3. We build and deploy the Debezium connector and the Amazon S3 sink using MSK Connect.

Example schema

For this post, we use the following schema as the first version of the table:

{ 
    “Database Name”: “sampledatabase”, 
    “Table Name”: “movies”, 
    “Fields”: [
         { 
            “name”: “movie_id”, 
            “type”: “INTEGER” 
         },
         { 
            “name”: “title”, 
            “type”: “STRING” 
         },
         { 
            “name”: “release_year”,
            “type”: “INTEGER” 
         }
     ] 
}

Prerequisites

Before configuring the MSK producer and consumer connectors, we need to first set up a data source, MSK cluster, and new schema registry. We provide an AWS CloudFormation template to generate the supporting resources needed for the solution:

  • A MySQL-compatible Aurora database as the data source. To perform CDC, we turn on binary logging in the DB cluster parameter group.
  • An MSK cluster. To simplify the network connection, we use the same VPC for the Aurora database and the MSK cluster.
  • Two schema registries to handle schemas for message key and message value.
  • One S3 bucket as the data sink.
  • MSK Connect plugins and worker configuration needed for this demo.
  • One Amazon Elastic Compute Cloud (Amazon EC2) instance to run database commands.

To set up resources in your AWS account, complete the following steps in an AWS Region that supports Amazon MSK, MSK Connect, and the AWS Glue Schema Registry:

  1. Choose Launch Stack:
  2. Choose Next.
  3. For Stack name, enter suitable name.
  4. For Database Password, enter the password you want for the database user.
  5. Keep other values as default.
  6. Choose Next.
  7. On the next page, choose Next.
  8. Review the details on the final page and select I acknowledge that AWS CloudFormation might create IAM resources.
  9. Choose Create stack.

Custom plugin for the source and destination connector

A custom plugin is a set of JAR files that contain the implementation of one or more connectors, transforms, or converters. Amazon MSK will install the plugin on the workers of the MSK Connect cluster where the connector is running. As part of this demo, for the source connector we use open-source Debezium MySQL connector JARs, and for the destination connector we use the Confluent community licensed Amazon S3 sink connector JARs. Both the plugins are also added with libraries for Avro Serializers and Deserializers of the AWS Glue Schema Registry. These custom plugins are already created as part of the CloudFormation template deployed in the previous step.

Use the AWS Glue Schema Registry with the Debezium connector on MSK Connect as the MSK producer

We first deploy the source connector using the Debezium MySQL plugin to stream data from an Amazon Aurora MySQL-Compatible Edition database to Amazon MSK. Complete the following steps:

  1. On the Amazon MSK console, in the navigation pane, under MSK Connect, choose Connectors.
  2. Choose Create connector.
  3. Choose Use existing custom plugin and then pick the custom plugin with name starting msk-blog-debezium-source-plugin.
  4. Choose Next.
  5. Enter a suitable name like debezium-mysql-connector and an optional description.
  6. For Apache Kafka cluster, choose MSK cluster and choose the cluster created by the CloudFormation template.
  7. In Connector configuration, delete the default values and use the following configuration key-value pairs and with the appropriate values:
    • name – The name used for the connector.
    • database.hostsname – The CloudFormation output for Database Endpoint.
    • database.user and database.password – The parameters passed in the CloudFormation template.
    • database.history.kafka.bootstrap.servers – The CloudFormation output for Kafka Bootstrap.
    • key.converter.region and value.converter.region – Your Region.
name=<Connector-name>
connector.class=io.debezium.connector.mysql.MySqlConnector
database.hostname=<DBHOST>
database.port=3306
database.user=<DBUSER>
database.password=<DBPASSWORD>
database.server.id=42
database.server.name=db1
table.whitelist=sampledatabase.movies
database.history.kafka.bootstrap.servers=<MSK-BOOTSTRAP>
database.history.kafka.topic=dbhistory.demo1
key.converter=com.amazonaws.services.schemaregistry.kafkaconnect.AWSKafkaAvroConverter
value.converter=com.amazonaws.services.schemaregistry.kafkaconnect.AWSKafkaAvroConverter
key.converter.region=<REGION>
value.converter.region=<REGION>
key.converter.registry.name=msk-connect-blog-keys
value.converter.registry.name=msk-connect-blog-values
key.converter.compatibility=FORWARD
value.converter.compatibility=FORWARD
key.converter.schemaAutoRegistrationEnabled=true
value.converter.schemaAutoRegistrationEnabled=true
transforms=unwrap
transforms.unwrap.type=io.debezium.transforms.ExtractNewRecordState
transforms.unwrap.drop.tombstones=false
transforms.unwrap.delete.handling.mode=rewrite
transforms.unwrap.add.fields=op,source.ts_ms
tasks.max=1

Some of these settings are generic and should be specified for any connector. For example:

  • connector.class is the Java class of the connector
  • tasks.max is the maximum number of tasks that should be created for this connector

Some settings (database.*, transforms.*) are specific to the Debezium MySQL connector. Refer to Debezium MySQL Source Connector Configuration Properties for more information.

Some settings (key.converter.* and value.converter.*) are specific to the Schema Registry. We use the AWSKafkaAvroConverter from the AWS Glue Schema Registry Library as the format converter. To configure AWSKafkaAvroConverter, we use the value of the string constant properties in the AWSSchemaRegistryConstants class:

  • key.converter and value.converter control the format of the data that will be written to Kafka for source connectors or read from Kafka for sink connectors. We use AWSKafkaAvroConverter for Avro format.
  • key.converter.registry.name and value.converter.registry.name define which schema registry to use.
  • key.converter.compatibility and value.converter.compatibility define the compatibility model.

Refer to Using Kafka Connect with AWS Glue Schema Registry for more information.

  1. Next, we configure Connector capacity. We can choose Provisioned and leave other properties as default
  2. For Worker configuration, choose the custom worker configuration with name starting msk-gsr-blog created as part of the CloudFormation template.
  3. For Access permissions, use the AWS Identity and Access Management (IAM) role generated by the CloudFormation template MSKConnectRole.
  4. Choose Next.
  5. For Security, choose the defaults.
  6. Choose Next.
  7. For Log delivery, select Deliver to Amazon CloudWatch Logs and browse for the log group created by the CloudFormation template (msk-connector-logs).
  8. Choose Next.
  9. Review the settings and choose Create connector.

After a few minutes, the connector changes to running status.

Use the AWS Glue Schema Registry with the Confluent S3 sink connector running on MSK Connect as the MSK consumer

We deploy the sink connector using the Confluent S3 sink plugin to stream data from Amazon MSK to Amazon S3. Complete the following steps:

    1. On the Amazon MSK console, in the navigation pane, under MSK Connect, choose Connectors.
    2. Choose Create connector.
    3. Choose Use existing custom plugin and choose the custom plugin with name starting msk-blog-S3sink-plugin.
    4. Choose Next.
    5. Enter a suitable name like s3-sink-connector and an optional description.
    6. For Apache Kafka cluster, choose MSK cluster and select the cluster created by the CloudFormation template.
    7. In Connector configuration, delete the default values provided and use the following configuration key-value pairs with appropriate values:
        • name – The same name used for the connector.
        • s3.bucket.name – The CloudFormation output for Bucket Name.
        • s3.region, key.converter.region, and value.converter.region – Your Region.
name=<CONNERCOR-NAME>
connector.class=io.confluent.connect.s3.S3SinkConnector
s3.bucket.name=<BUCKET-NAME>
key.converter=com.amazonaws.services.schemaregistry.kafkaconnect.AWSKafkaAvroConverter
value.converter=com.amazonaws.services.schemaregistry.kafkaconnect.AWSKafkaAvroConverter
s3.region=<REGION>
storage.class=io.confluent.connect.s3.storage.S3Storage
partitioner.class=io.confluent.connect.storage.partitioner.DefaultPartitioner
format.class=io.confluent.connect.s3.format.parquet.ParquetFormat
flush.size=10
tasks.max=1
key.converter.schemaAutoRegistrationEnabled=true
value.converter.schemaAutoRegistrationEnabled=true
key.converter.region=<REGION>
value.converter.region=<REGION>
value.converter.avroRecordType=GENERIC_RECORD
key.converter.avroRecordType=GENERIC_RECORD
value.converter.compatibility=NONE
key.converter.compatibility=NONE
store.kafka.keys=false
schema.compatibility=NONE
topics=db1.sampledatabase.movies
value.converter.registry.name=msk-connect-blog-values
key.converter.registry.name=msk-connect-blog-keys
store.kafka.headers=false
  1. Next, we configure Connector capacity. We can choose Provisioned and leave other properties as default
  2. For Worker configuration, choose the custom worker configuration with name starting msk-gsr-blog created as part of the CloudFormation template.
  3. For Access permissions, use the IAM role generated by the CloudFormation template MSKConnectRole.
  4. Choose Next.
  5. For Security, choose the defaults.
  6. Choose Next.
  7. For Log delivery, select Deliver to Amazon CloudWatch Logs and browse for the log group created by the CloudFormation template msk-connector-logs.
  8. Choose Next.
  9. Review the settings and choose Create connector.

After a few minutes, the connector is running.

Test the end-to-end CDC log stream

Now that both the Debezium and S3 sink connectors are up and running, complete the following steps to test the end-to-end CDC:

  1. On the Amazon EC2 console, navigate to the Security groups page.
  2. Select the security group ClientInstanceSecurityGroup and choose Edit inbound rules.
  3. Add an inbound rule allowing SSH connection from your local network.
  4. On the Instances page, select the instance ClientInstance and choose Connect.
  5. On the EC2 Instance Connect tab, choose Connect.
  6. Ensure your current working directory is /home/ec2-user and it has the files create_table.sql, alter_table.sql , initial_insert.sql, and insert_data_with_new_column.sql.
  7. Create a table in your MySQL database by running the following command (provide the database host name from the CloudFormation template outputs):
mysql -h <DATABASE-HOST> -u master -p < create_table.sql
  1. When prompted for a password, enter the password from the CloudFormation template parameters.
  2. Insert some sample data into the table with the following command:
mysql -h <DATABASE-HOST> -u master -p < initial_insert.sql
  1. When prompted for a password, enter the password from the CloudFormation template parameters.
  2. On the AWS Glue console, choose Schema registries in the navigation pane, then choose Schemas.
  3. Navigate to db1.sampledatabase.movies version 1 to check the new schema created for the movies table:
{
  "type": "record",
  "name": "Value",
  "namespace": "db1.sampledatabase.movies",
  "fields": [
    {
      "name": "movie_id",
      "type": "int"
    },
    {
      "name": "title",
      "type": "string"
    },
    {
      "name": "release_year",
      "type": "int"
    },
    {
      "name": "__op",
      "type": [
        "null",
        "string"
      ],
      "default": null
    },
    {
      "name": "__source_ts_ms",
      "type": [
        "null",
        "long"
      ],
      "default": null
    },
    {
      "name": "__deleted",
      "type": [
        "null",
        "string"
      ],
      "default": null
    }
  ],
  "connect.name": "db1.sampledatabase.movies.Value"
}

A separate S3 folder is created for each partition of the Kafka topic, and data for the topic is written in that folder.

  1. On the Amazon S3 console, check for data written in Parquet format in the folder for your Kafka topic.

Schema evolution

After the initial schema is defined, applications may need to evolve it over time. When this happens, it’s critical for the downstream consumers to be able to handle data encoded with both the old and the new schema seamlessly. Compatibility modes allow you to control how schemas can or can’t evolve over time. These modes form the contract between applications producing and consuming data. For detailed information about different compatibility modes available in the AWS Glue Schema Registry, refer to AWS Glue Schema Registry. In our example, we use backward combability to ensure consumers can read both the current and previous schema versions. Complete the following steps:

  1. Add a new column to the table by running the following command:
mysql -h <DATABASE-HOST> -u master -p < alter_table.sql
  1. Insert new data into the table by running the following command:
mysql -h <DATABASE-HOST> -u master -p < insert_data_with_new_column.sql
  1. On the AWS Glue console, choose Schema registries in the navigation pane, then choose Schemas.
  2. Navigate to the schema db1.sampledatabase.movies version 2 to check the new version of the schema created for the movies table movies including the country column that you added:
{
  "type": "record",
  "name": "Value",
  "namespace": "db1.sampledatabase.movies",
  "fields": [
    {
      "name": "movie_id",
      "type": "int"
    },
    {
      "name": "title",
      "type": "string"
    },
    {
      "name": "release_year",
      "type": "int"
    },
    {
      "name": "COUNTRY",
      "type": "string"
    },
    {
      "name": "__op",
      "type": [
        "null",
        "string"
      ],
      "default": null
    },
    {
      "name": "__source_ts_ms",
      "type": [
        "null",
        "long"
      ],
      "default": null
    },
    {
      "name": "__deleted",
      "type": [
        "null",
        "string"
      ],
      "default": null
    }
  ],
  "connect.name": "db1.sampledatabase.movies.Value"
}
  1. On the Amazon S3 console, check for data written in Parquet format in the folder for the Kafka topic.

Clean up

To help prevent unwanted charges to your AWS account, delete the AWS resources that you used in this post:

  1. On the Amazon S3 console, navigate to the S3 bucket created by the CloudFormation template.
  2. Select all files and folders and choose Delete.
  3. Enter permanently delete as directed and choose Delete objects.
  4. On the AWS CloudFormation console, delete the stack you created.
  5. Wait for the stack status to change to DELETE_COMPLETE.

Conclusion

This post demonstrated how to use Amazon MSK, MSK Connect, and the AWS Glue Schema Registry to build a CDC log stream and evolve schemas for data streams as business needs change. You can apply this architecture pattern to other data sources with different Kafka connecters. For more information, refer to the MSK Connect examples.


About the Author

Kalyan Janaki is Senior Big Data & Analytics Specialist with Amazon Web Services. He helps customers architect and build highly scalable, performant, and secure cloud-based solutions on AWS.
How to use policies to restrict where EC2 instance credentials can be used from

Post Syndicated from Liam Wadman original https://aws.amazon.com/blogs/security/how-to-use-policies-to-restrict-where-ec2-instance-credentials-can-be-used-from/

Today AWS launched two new global condition context keys that make it simpler for you to write policies in which Amazon Elastic Compute Cloud (Amazon EC2) instance credentials work only when used on the instance to which they are issued. These new condition keys are available today in all AWS Regions, as well as AWS GovCloud and China partitions.

Using these new condition keys, you can write service control policies (SCPs) or AWS Identity and Access Management (IAM) policies that restrict the virtual private clouds (VPCs) and private IP addresses from which your EC2 instance credentials can be used, without hard-coding VPC IDs or IP addresses in the policy. Previously, you had to list specific VPC IDs and IP addresses in the policy if you wanted to use it to restrict where EC2 credentials were used. With this new approach, you can use less policy space and reduce the time spent on updates when your list of VPCs and network ranges changes.

In this blog post, we will show you how to use these new condition keys in an SCP and a resource policy to help ensure that the IAM role credentials assigned to your EC2 instances can only be used from the instances to which they were issued.

New global condition keys

The two new condition keys are as follows:

  • aws:EC2InstanceSourceVPC — This single-valued condition key contains the VPC ID to which an EC2 instance is deployed.
  • aws:EC2InstanceSourcePrivateIPv4 — This single-valued condition key contains the primary IPv4 address of an EC2 instance.

These new conditions are available only for use with credentials issued to an EC2 instance. You don’t have to make configuration changes to activate the new condition keys.

Let’s start by reviewing some existing IAM conditions and how to combine them with the new conditions. When requests are made to an AWS service over a VPC endpoint, the value of the aws:SourceVpc condition key is the ID of the VPC into which the endpoint is deployed. The value of the aws:VpcSourceIP condition key is the IP address from which the endpoint receives the request. The aws:SourceVpc and aws:VpcSourceIP keys are null when requests are made through AWS public service endpoints. These condition keys relate to dynamic properties of the network path by which your AWS Signature Version 4-signed request reached the API endpoint. For a list of AWS services that support VPC endpoints, see AWS services that integrate with AWS PrivateLink.

The two new condition keys relate to dynamic properties of the EC2 role credential itself. By using the two new credential-relative condition keys with the existing network path-relative aws:SourceVPC and aws:VpcSourceIP condition keys, you can create SCPs to help ensure that credentials for EC2 instances are only used from the EC2 instances to which they were issued. By writing policies that compare the two sets of dynamic values, you can configure your environment such that requests signed with an EC2 instance credential are denied if they are used anywhere other than the EC2 instance to which they were issued.

Policy examples

In the following SCP example, access is denied if the value of aws:SourceVpc is not equal to the value of aws:ec2InstanceSourceVPC, or if the value of aws:VpcSourceIp is not equal to the value of aws:ec2InstanceSourcePrivateIPv4. The policy uses aws:ViaAWSService to allow certain AWS services to take action on your behalf when they use your role’s identity to call services, such as when Amazon Athena queries Amazon Simple Storage Service (Amazon S3).

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Deny",
      "Action": "*",
      "Resource": "*",
      "Condition": {
        "StringNotEquals": {
          "aws:ec2InstanceSourceVPC": "${aws:SourceVpc}"
        },
        "Null": {
          "ec2:SourceInstanceARN": "false"
        },
        "BoolIfExists": {
          "aws:ViaAWSService": "false"
        }
      }
    },
    {
      "Effect": "Deny",
      "Action": "*",
      "Resource": "*",
      "Condition": {
        "StringNotEquals": {
          "aws:ec2InstanceSourcePrivateIPv4": "${aws:VpcSourceIp}"
        },
        "Null": {
          "ec2:SourceInstanceARN": "false"
        },
        "BoolIfExists": {
          "aws:ViaAWSService": "false"
        }
      }
    }
  ]
}

Because we encase aws:SourceVpc and aws:VpcSourceIp in “${}” in these policies, they are treated as a variable using the value in the request being made. However, in the IAM policy language, the operator on the left side of a comparison is implicitly treated as a variable, while the operator on the right side must be explicitly declared as a variable. The “Null” operator on the ec2:SourceInstanceARN condition key is designed to ensure that this policy only applies to EC2 instance roles, and not roles used for other purposes, such as those used in AWS Lambda functions.

The two deny statements in this example form a logical “or” statement, such that either a request from a different VPC or a different IP address evaluates in a deny. But functionally, they act in an “and” fashion. To be allowed, a request must satisfy both the VPC-based and the IP-based conditions because failure of either denies the call. Because VPC IDs are globally unique values, it’s reasonable to use the VPC-based condition without the private IP condition. However, you should avoid evaluating only the private IP condition without also evaluating the VPC condition. Private IPs can be the same across different environments, so aws:ec2InstanceSourcePrivateIPv4 is safe to use only in conjunction with the VPC-based condition.

Note: SCPs do not grant IAM permissions; they only remove them. Thus, you must permit your EC2 instances to use AWS services by using IAM policies associated with their roles. For more information, see Determining whether a request is allowed or denied within an account.

If you have specific EC2 instance roles that you want to exclude from the statement, you can apply exception logic through tags or role names.

The following example applies to roles used as EC2 instance roles, except those with a tag of exception-to-vpc-ip where the value is equal to true by using the aws:PrincipalTag condition key. The three condition operators (StringNotEquals, Null, and BoolIfExists) in the same condition block are evaluated with a logical AND operation, and if either of the tests doesn’t evaluate, then the deny statement doesn’t apply. Hence, EC2 instance roles with a principal tag of exception-to-vpc-ip equal to true are not subject to this SCP.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Deny",
      "Action": "*",
      "Resource": "*",
      "Condition": {
        "StringNotEquals": {
          "aws:ec2InstanceSourceVPC": "${aws:SourceVpc}",
          "aws:PrincipalTag/exception-to-vpc-ip": "true"
        },
        "Null": {
          "ec2:SourceInstanceARN": "false"
        },
        "BoolIfExists": {
          "aws:ViaAWSService": "false"
        }
      }
    },
    {
      "Effect": "Deny",
      "Action": "*",
      "Resource": "*",
      "Condition": {
        "StringNotEquals": {
          "aws:ec2InstanceSourcePrivateIPv4": "${aws:VpcSourceIp}",
           "aws:principaltag/exception-to-vpc-ip": "true"
        },
        "Null": {
          "ec2:SourceInstanceARN": "false"
        },
        "BoolIfExists": {
          "aws:ViaAWSService": "false"
        }
      }
    }
  ]
}

You can apply exception logic to other attributes of your IAM roles. For example, you can use the aws:PrincipalArn condition key to exempt certain roles based on their AWS account. You can also specify where you want this SCP to be applied in your AWS Organizations organization. You can apply SCPs directly to accounts, organizational units, or organizational roots. For more information about inheritance when applying SCPs in Organizations, see Understanding policy inheritance.

You can also apply exception logic to your SCP statements at the IAM Action. The following example statement restricts an EC2 instance’s credential usage to only the instance from which it was issued, except for calls to IAM by using a NotAction element. You should use this exception logic if an AWS service doesn’t have a VPC endpoint, or if you don’t want to use VPC endpoints to access a particular service.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Deny",
      "NotAction": "iam:*",
      "Resource": "*",
      "Condition": {
        "StringNotEquals": {
          "aws:ec2InstanceSourceVPC": "${aws:SourceVpc}"
        },
        "Null": {
          "ec2:SourceInstanceARN": "false"
        },
        "BoolIfExists": {
          "aws:ViaAWSService": "false"
        }
      }
    },
    {
      "Effect": "Deny",
      "NotAction": "iam:*",
      "Resource": "*",
      "Condition": {
        "StringNotEquals": {
          "aws:ec2InstanceSourcePrivateIPv4": "${aws:VpcSourceIp}"
        },
        "Null": {
          "ec2:SourceInstanceARN": "false"
        },
        "BoolIfExists": {
          "aws:ViaAWSService": "false"
        }
      }
    }
  ]
}

Because these new condition keys are global condition keys, you can use the keys in all relevant AWS policy types, such as the following policy for an S3 bucket. When using this as a bucket policy, make sure to replace <DOC-EXAMPLE-BUCKET> with the ARN of your S3 bucket.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Deny",
      "Action": "s3:*",
      "Principal": {
        "AWS": "*"
      },
      "Resource": [
        "arn:aws:s3:::<DOC-EXAMPLE-BUCKET>/*",
        "arn:aws:s3::: <DOC-EXAMPLE-BUCKET>"
      ],
      "Condition": {
        "StringNotEquals": {
          "aws:ec2InstanceSourceVPC": "${aws:SourceVpc}"
        },
        "Null": {
          "ec2:SourceInstanceARN": "false"
        },
        "BoolIfExists": {
          "aws:ViaAWSService": "false"
        }
      }
    },
    {
      "Effect": "Deny",
      "Action": "*",
      "Principal": {
        "AWS": "*"
      },
      "Resource": [
        "arn:aws:s3::: <DOC-EXAMPLE-BUCKET> /*",
        "arn:aws:s3::: <DOC-EXAMPLE-BUCKET>"
      ],
      "Condition": {
        "StringNotEquals": {
          "aws:ec2InstanceSourcePrivateIPv4": "${aws:VpcSourceIp}"
        },
        "Null": {
          "ec2:SourceInstanceARN": "false"
        },
        "BoolIfExists": {
          "aws:ViaAWSService": "false"
        }
      }
    }
  ]
}

This policy restricts access to your S3 bucket to EC2 instance roles that are used only from the instance to which they were vended. Like the previous policy examples, there are two deny statements in this example to form a logical “or” statement but a functional “and” statement, because a request must come from the same VPC and same IP address of the instance that it was issued to, or else it evaluates to a deny.

Conclusion

In this blog post, you learned about the newly launched aws:ec2InstanceSourceVPC and aws:ec2InstanceSourcePrivateIPv4 condition keys. You also learned how to use them with SCPs and resource policies to limit the usage of your EC2 instance roles to the instances from which they originated when requests are made over VPC endpoints. Because these new condition keys are global condition keys, you can use them in all relevant AWS policy types. These new condition keys are available today in all Regions, as well as AWS GovCloud and China partitions.

If you have questions, comments, or concerns, contact AWS Support or start a new thread at AWS Identity and Access Management or Compute re:Post.

If you have feedback about this post, submit comments in the Comments section below.

Liam Wadman

Liam Wadman

Liam is a Solutions Architect with the Identity Solutions team. When he’s not building exciting solutions on AWS or helping customers, he’s often found in the hills of British Columbia on his Mountain Bike. Liam points out that you cannot spell LIAM without IAM.

Joshua Levinson

Joshua Levinson

Joshua is a Senior Product Manager at AWS on the EC2 team. He is passionate about helping customers with highly scalable features on EC2 and across AWS, and enjoys the challenge of building simplified solutions to complex problems. Outside of work, he enjoys cooking, reading with his kids, and Olympic weightlifting.

How to set up least privilege access to your encrypted Amazon SQS queue

Post Syndicated from Ahmed Bakry original https://aws.amazon.com/blogs/security/how-to-set-up-least-privilege-access-to-your-encrypted-amazon-sqs-queue/

Amazon Simple Queue Service (Amazon SQS) is a fully-managed message queueing service that enables you to decouple and scale microservices, distributed systems, and serverless applications. Amazon SQS provides authentication mechanisms so that you can control who has access to the queue. It also provides encryption in transit with HTTP over SSL or TLS, and it supports server-side encryption using AWS Key Management Service (AWS KMS) to help protect the data passing through Amazon SQS. These controls allow you to use Amazon SQS to exchange sensitive data between applications. With the integration of Amazon SQS and AWS KMS, you can centrally-manage the keys that protect Amazon SQS, as well as the keys that protect your other AWS resources.

AWS services, such as Amazon Simple Storage Service (Amazon S3) and Amazon Simple Notification Service (Amazon SNS), can act as event sources that send events to Amazon SQS. To enable an event source to access an encrypted SQS queue, you will need to configure the queue with a customer managed key in AWS KMS, and then use the key policy to allow the event source to use the required AWS KMS API methods. The event source also requires permissions to authenticate access to the queue to send events. You can achieve this by using an SQS policy, which is a resource-based policy that you can use to control access to the SQS queue and its data.

In this blog post, we will show you how to control access to your encrypted SQS queue through the key policy and the SQS policy. The policies introduced in this post will guide you towards achieving least privilege. We will also describe how the resource-based policies defined in this post address the confused deputy problem by using the aws:SourceArn, aws:SourceAccount, and aws:PrincipalOrgID global AWS Identity and Access Management (IAM) condition context keys.

Solution overview

In this post, we will walk you through a common use case to illustrate how you can build the key policy and the SQS queue policy. This use case is shown in Figure 1.

Figure 1: Architecture to publish Amazon SNS messages to Amazon SQS

Figure 1: Architecture to publish Amazon SNS messages to Amazon SQS

As shown in Figure 1, the solution has the following steps:

  1. The message producer is an Amazon SNS topic. The topic is configured to send messages to an encrypted Amazon SQS queue. The queue is encrypted by using an AWS KMS customer-managed key.
  2. The message consumer is a compute service such as an AWS Lambda function, an Amazon Elastic Compute Cloud (Amazon EC2) instance, or an AWS Fargate container. The message consumer is configured to process messages from the queue.
  3. The SQS queue is configured to send failed messages to a dead-letter queue (DLQ). This can help you debug your application or messaging system because DLQs let you isolate unconsumed messages to determine why their processing didn’t succeed.

Note: If the message consumer is located in an Amazon Virtual Private Cloud (Amazon VPC) and you need to restrict message reception to that specific VPC, then you should attach the DenyReceivingIfNotThroughVPCE policy statement to your SQS queue policy.

The SQS policy defined in this post doesn’t support redriving messages directly to the same or a different SQS queue.

Prerequisites

This post contains only the required IAM permissions in the form of policy statements. To construct the policy, you need to add the statements to your SQS policy or your AWS KMS key policy. This post doesn’t walk you through how to create the SQS queue or the AWS KMS key. Therefore, to use the policies included in this post, make sure that you’ve completed the following prerequisites:

  1. Set up an SQS queue. For instructions, see Create a queue (console) in the Amazon SQS documentation.
  2. Create an AWS KMS key. For instructions, see Creating keys in the AWS KMS documentation.

Least-privilege key policy for Amazon SQS

In this section, we describe the required least-privilege permissions in AWS KMS for the customer-managed key that you use to encrypt your SQS queue. With these permissions, you can limit access to only the intended entities while implementing least privilege. The key policy must consist of the following policy statements, which we describe in detail below:

  • Grant administrator permissions to the KMS key
  • Grant read-only access to the key metadata
  • Grant AWS KMS permissions to Amazon SNS to publish messages to the queue
  • Allow consumers to decrypt messages from the queue

Grant administrator permissions to the KMS key

To create an AWS KMS key, you need to provide AWS KMS administrator permissions to the IAM role that you use to deploy the KMS key. These administrator permissions are defined in the AllowKeyAdminPermissions policy statement that follows. When you add this statement to your key policy, make sure to replace <admin-role ARN> with the Amazon Resource Name (ARN) of the IAM role used to deploy the KMS key, manage the KMS key, or both. This can be the IAM role of your deployment pipeline or the administrator role for your organization in AWS Organizations.

{
  "Sid": "AllowKeyAdminPermissions",
  "Effect": "Allow",
  "Principal": {
    "AWS": [
      "<admin-role ARN>"
    ]
  },
  "Action": [
    "kms:Create*",
    "kms:Describe*",
    "kms:Enable*",
    "kms:List*",
    "kms:Put*",
    "kms:Update*",
    "kms:Revoke*",
    "kms:Disable*",
    "kms:Get*",
    "kms:Delete*",
    "kms:TagResource",
    "kms:UntagResource",
    "kms:ScheduleKeyDeletion",
    "kms:CancelKeyDeletion"
  ],
  "Resource": "*"
}

Note: In a key policy, the value of the Resource element needs to be “*”, which means “this KMS key”. The asterisk (“*”) identifies the KMS key to which the key policy is attached.

Grant read-only access to the key metadata

To grant other IAM roles read-only access to your key metadata, add the following AllowReadAccessToKeyMetaData statement to your key policy. This statement allows you, for example, to list the KMS keys in your account for auditing purposes. The statement grants the AWS account root user read-only access to the key metadata. Therefore, an IAM principal in the account can have access to the key metadata when their identity-based policies have the following permissions listed in the statement: kms:Describe*, kms:Get*, and kms:List*. Make sure to replace <account-ID> with your own information.

{
  "Sid": "AllowReadAcesssToKeyMetaData",
  "Effect": "Allow",
  "Principal": {
    "AWS": [
      "arn:aws:iam::<account-ID>:root"
    ]
  },
  "Action": [
    "kms:Describe*",
    "kms:Get*",
    "kms:List*"
  ],
  "Resource": "*"
}

Grant AWS KMS permissions to Amazon SNS to publish messages to the queue

To allow your SNS topic to publish messages to your encrypted SQS queue, add the following AllowSNSToSendToSQS policy statement to your key policy. This statement grants Amazon SNS permissions to use the KMS key to publish to your SQS queue. Make sure to replace <account-id> with your own information.

Note: The Condition element limits access to the SNS service in the same AWS account where the SNS topic exists.

{
  "Sid": "AllowSNSToSendToSQS",
  "Effect": "Allow",
  "Principal": {
    "Service": [
      "sns.amazonaws.com"
    ]
  },
  "Action": [
    "kms:GenerateDataKey",
    "kms:Decrypt"
  ],
  "Resource": "*",
  "Condition": {
    "StringEquals": {
      "aws:SourceAccount": "<account-id>"
    }
  }
}

Allow consumers to decrypt messages from the queue

The following AllowConsumersToReceiveFromTheQueue statement grants the SQS message consumer the required permissions to decrypt messages received from the encrypted SQS queue. When you attach the policy statement, replace <consumer’s runtime role ARN> with the ARN for the IAM runtime role of the message consumer.

{
  "Sid": "AllowConsumersToReceiveFromTheQueue",
  "Effect": "Allow",
  "Principal": {
    "AWS": [
      "<consumer's runtime role ARN>"
    ]
  },
  "Action": [
    "kms:Decrypt"
  ],
  "Resource": "*"
}

Least-privilege Amazon SQS policy

In this section, we will walk you through least-privilege SQS queue policies to help you send Amazon SNS messages to Amazon SQS. The defined policy is designed to prevent unintended access by using a mix of both allow and deny statements. The allow statements grant access to the intended entity or entities. The deny statements prevent other unintended entities from accessing the SQS queue, while excluding the intended entity within the policy condition. The SQS policy includes the following statements, which we describe in detail below:

  • Restrict Amazon SQS management permissions
  • Restrict SQS queue actions from the specified organization
  • Grant SQS permissions to consumers
  • Enforce encryption in transit
  • Restrict message transmission to a specific SNS topic
  • (Optional) Restrict message reception to a specific VPC endpoint

Restrict Amazon SQS management permissions

The following RestrictAdminQueueActions policy statement restricts the Amazon SQS management permissions to only the IAM role or roles that you use to deploy the queue, manage the queue, or both.

Make sure to replace the <placeholder values> with your own information. Specify the ARN of the IAM role used to deploy the SQS queue, as well as the ARNs of each administrator role that should have SQS management permissions. For the Resource element, you can specify either “*” or the ARN of the SQS queue.

{
  "Sid": "RestrictAdminQueueActions",
  "Effect": "Deny",
  "Principal": {
    "AWS": "*"
  },
  "Action": [
    "sqs:AddPermission",
    "sqs:DeleteQueue",
    "sqs:RemovePermission",
    "sqs:SetQueueAttributes"
  ],
  "Resource": "*",
  "Condition": {
    "StringNotLike": {
      "aws:PrincipalARN": [
        "arn:aws:iam::<account-id>:role/<deployment-role-name>",
        "<admin-role ARN>"
      ]
    }
  }
}

Restrict SQS queue actions from the specified organization

To help protect your Amazon SQS resources from external access (that is, access by an entity outside your AWS Organizations organization), use the following statement. The statement limits SQS queue access to the organization that you specify in the Condition element. Make sure to replace <org-id> with your organization ID. For the Resource element, you can specify either “*” or the ARN of the SQS queue.

{
  "Sid": "DenyQueueActionsOutsideOrg",
  "Effect": "Deny",
  "Principal": {
    "AWS": "*"
  },
  "Action": [
    "sqs:AddPermission",
    "sqs:ChangeMessageVisibility",
    "sqs:DeleteQueue",
    "sqs:RemovePermission",
    "sqs:SetQueueAttributes",
    "sqs:ReceiveMessage"
  ],
  "Resource": "*",
  "Condition": {
    "StringNotEquals": {
      "aws:PrincipalOrgID": [
        "<org-id>"
      ]
    }
  }
}

Grant SQS permissions to consumers

To receive messages from the SQS queue, you need to provide the message consumer with the necessary permissions. The following policy statement grants the consumer, which you specify, the required permissions to consume messages from the SQS queue. When adding the statement to your SQS policy, make sure to replace <consumer’s IAM runtime role ARN> with the ARN of the IAM runtime role used by the consumer. For the Resource element, you can specify either “*” or the ARN of the SQS queue.

{
  "Sid": "AllowConsumersToReceiveFromTheQueue",
  "Effect": "Allow",
  "Principal": {
    "AWS": "<consumer's IAM runtime role ARN>"
  },
  "Action": [
    "sqs:ChangeMessageVisibility",
    "sqs:DeleteMessage",
    "sqs:GetQueueAttributes",
    "sqs:ReceiveMessage"
  ],
  "Resource": "*"
}

To prevent other entities from receiving messages from the SQS queue, add the following DenyOtherConsumersFromReceiving statement to the SQS queue policy. This statement restricts message consumption to the consumer that you specify—allowing no other consumer to have access, even when their identity permissions would grant them access. Make sure to replace <consumer’s runtime role ARN> with your own information. For the Resource element, you can specify either “*” or the ARN of the SQS queue.

{
  "Sid": "DenyOtherConsumersFromReceiving",
  "Effect": "Deny",
  "Principal": {
    "AWS": "*"
  },
  "Action": [
    "sqs:ChangeMessageVisibility",
    "sqs:DeleteMessage",
    "sqs:ReceiveMessage"
  ],
  "Resource": "*",
  "Condition": {
    "StringNotLike": {
      "aws:PrincipalARN": "<consumer's runtime role ARN>"
    }
  }
}

Enforce encryption in transit

The following DenyUnsecureTransport policy statement enforces the consumers and producers to use secure channels (TLS connections) to send and receive messages to and from the SQS queue. For the Resource element, you can specify either “*” or the ARN of the SQS queue.

{
  "Sid": "DenyUnsecureTransport",
  "Effect": "Deny",
  "Principal": {
    "AWS": "*"
  },
  "Action": [
    "sqs:ReceiveMessage",
    "sqs:SendMessage"
  ],
  "Resource": "*",
  "Condition": {
    "Bool": {
      "aws:SecureTransport": "false"
    }
  }
}

Restrict message transmission to a specific SNS topic

The following AllowSNSToSendToTheQueue policy statement allows the specified SNS topic to send messages to the SQS queue. Make sure to replace <SNS topic ARN> with the SNS topic ARN. For the Resource element, you can specify either “*” or the ARN of the SQS queue.

{
  "Sid": "AllowSNSToSendToTheQueue",
  "Effect": "Allow",
  "Principal": {
    "Service": "sns.amazonaws.com"
  },
  "Action": "sqs:SendMessage",
  "Resource": "*",
  "Condition": {
    "ArnLike": {
      "aws:SourceArn": "<SNS topic ARN>"
    }
  }
}

The following DenyAllProducersExceptSNSFromSending policy statement prevents other producers from sending messages to the queue. Replace <SNS topic ARN> with your own information. For the Resource element, you can specify either “*” or the ARN of the SQS queue.

{
  "Sid": "DenyAllProducersExceptSNSFromSending",
  "Effect": "Deny",
  "Principal": {
    "AWS": "*"
  },
  "Action": "sqs:SendMessage",
  "Resource": "*",
  "Condition": {
    "ArnNotLike": {
      "aws:SourceArn": "<SNS topic ARN>"
    }
  }
}

(Optional) Restrict message reception to a specific VPC endpoint

To restrict the receipt of messages to only a specific VPC endpoint, add the following DenyReceivingIfNotThroughVPCE policy statement to your SQS queue policy. This statement prevents a message consumer from receiving messages from the queue unless the messages are from the desired VPC endpoint. Replace <vpce_id> with the ID of the VPC endpoint that you created for your SQS queue. For the Resource element, you can specify either “*” or the ARN of the SQS queue.

{
  "Sid": "DenyReceivingIfNotThroughVPCE",
  "Effect": "Deny",
  "Principal": "*",
  "Action": [
    "sqs:ReceiveMessage"
  ],
  "Resource": "*",
  "Condition": {
    "StringNotEquals": {
      "aws:sourceVpce": "<vpce id>"
    }
  }
}

SQS policy statements for the dead-letter queue

In this section, we will walk you through how to manage access to your SQS queue when you are using it as a dead-letter queue (DLQ) for another SQS queue.

Add policy statements to your DLQ access policy

Add the following policy statements, identified by their statement ID, to your DLQ access policy. These are the same policy statements introduced earlier in this post.

  • RestrictAdminQueueActions
  • DenyQueueActionsOutsideOrg
  • AllowConsumersToReceiveFromTheQueue
  • DenyOtherConsumersFromReceiving
  • DenyUnsecureTransport

In addition to adding the preceding policy statements to your DLQ access policy, you should add a statement to restrict message transmission to SQS queues, which we describe in the next section.

Restrict message transmission to SQS queues

To restrict access to only SQS queues from the same account, add the following DenyAnyProducersExceptSQS policy statement to the DLQ access policy. This statement doesn’t limit message transmission to a specific queue because you need to deploy the DLQ before you create the main queue, so you won’t know the SQS queue ARN when you create the DLQ. If you need to limit access to only one SQS queue, modify the aws:SourceArn in the Condition element with the ARN of your SQS source queue when you know it.

{
  "Sid": "DenyAnyProducersExceptSQS",
  "Effect": "Deny",
  "Principal": {
    "AWS": "*"
  },
  "Action": "sqs:SendMessage",
  "Resource": "*",
  "Condition": {
    "ArnNotLike": {
      "aws:SourceArn": "arn:aws:sqs:<region>:<account-id>:*"
    }
  }
}

Important: The SQS queue policies defined in this post don’t restrict the sqs:PurgeQueue action to a certain IAM role or roles. The sqs:PurgeQueue action enables you to delete all messages in the SQS queue. You can also use this action to make changes to the message format without replacing the SQS queue. When debugging an application, you can clear the SQS queue to remove potentially erroneous messages. When testing the application, you can drive a high message volume through the SQS queue and then purge the queue to start fresh before entering production. The reason for not restricting this action to a certain role is that this role might not be known when deploying the SQS queue. You will need to add this permission to the role’s identity-based policy to be able to purge the queue.

Prevent the cross-service confused deputy problem

The confused deputy problem is a security issue where an entity that doesn’t have permission to perform an action can coerce a more privileged entity to perform the action. To help prevent this problem, AWS provides tools that help you protect your account if you provide third parties (known as cross-account) or other AWS services (known as cross-service) access to resources in your account. The policy statements in this post can help you prevent the cross-service confused deputy problem.

Cross-service impersonation can occur when one service (the calling service) calls another service (the called service). The calling service can be manipulated to use its permissions to act on another customer’s resources in a way it shouldn’t otherwise have permission to access. To help protect against this issue, the resource-based policies defined in this post use the aws:SourceArn, aws:SourceAccount, and aws:PrincipalOrgID global IAM condition context keys. These limit the permissions that a service has to a specific resource, a specific account, or a specific organization in AWS Organizations.

For example, the following AllowS3ToSendToTheQueue policy statement allows Amazon S3 to deliver messages to your Amazon SQS queue; the aws:SourceArn condition in this policy grants access to a specific S3 bucket only.

{
  "Sid": "AllowS3ToSendToTheQueue",
  "Effect": "Allow",
  "Principal": {
    "Service": "s3.amazonaws.com"
  },
  "Action": "sqs:SendMessage",
  "Resource": "*",
  "Condition": {
    "ArnLike": {
      "aws:SourceArn": "<S3 bucket ARN>"
    }
  }
}

If a bad actor creates an S3 bucket to try to deliver messages to your Amazon SQS queue, the source ARN will not match that of the S3 bucket specified in this policy, so the policy will deny access. Without the aws:SourceArn condition, the unauthorized S3 bucket would be granted access unintentionally because any S3 bucket would be granted to deliver messages to our queue through the S3 service principal. Adding the aws:SourceArn condition prevents cross-service impersonation.

Use IAM Access Analyzer to review cross-account access

You can use IAM Access Analyzer to review your SQS queue policies and AWS KMS key policies and alert you when an SQS queue or a KMS key grants access to an external entity. IAM Access Analyzer helps identify resources in your organization and accounts that are shared with an entity outside the zone of trust. This zone of trust can be either an AWS account or the organization within AWS Organizations that you specify when you enable IAM Access Analyzer.

IAM Access Analyzer also helps identify resources shared with external principals by using logic-based reasoning to analyze the resource-based policies in your AWS environment. For each instance of a resource shared outside of your zone of trust, IAM Access Analyzer generates a finding. Figure 2 shows an IAM Access Analyzer finding, in which a sqs:SendMessage API call was made to our SQS queue from an account that is outside of our zone of trust.

Figure 2: IAM Access Analyzer example finding for an Amazon SQS queue

Figure 2: IAM Access Analyzer example finding for an Amazon SQS queue

Findings include information about the access and the external principal granted to it. To determine whether the access is intended and safe, or unintended and a security risk, review the findings. For unintended access, review the affected policy and modify it by using the policy statements introduced in this blog post to further restrict access. For more information on how IAM Access Analyzer identifies unintended access to your AWS resources, see the blog post Identify Unintended Resource Access with IAM Access Analyzer.

Conclusion

In this post, you learned how to manage access to your encrypted Amazon SQS queue to help you achieve least privilege. We presented an SQS queue policy and an AWS KMS key policy so that you can use Amazon SQS to receive messages from an SNS topic. We addressed the confused deputy problem, specifying the exact source allowed to emit events. You also learned how to use IAM Access Analyzer to review the external access provided by your existing SQS queue policies and key policies.

You can follow the instructions in this post to resolve findings based on your SQS use case. You can also use the provided policies for newly created SQS queues and their KMS keys, or to modify existing queues (for example, to address IAM Access Analyzer findings). For more use cases, see the AWS SQS documentation.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the Amazon Simple Queue Service re:Post or contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Ahmed Bakry

Ahmed Bakry

Ahmed Bakry is a Security Consultant at AWS Professional Services and based in Amsterdam. He obtained his master’s degree in Computer Science at the University of Twente and specialized in Cyber Security. And he did his bachelor degree in Networks Engineering at the German University in Cairo. His passion is developing secure and robust applications that drive success for his customers.

Simon Kok

Simon Kok

Simon is a Senior Application Developer Consultant at AWS Professional Services. He works with Enterprise AWS customers to help them refactor, improve, and extend applications. Allowing them to achieve their business goals and scale using modern best practices. He combines this with a passion for security.

Yury Brukau

Yury Brukau

Yury is a Cloud Application Architect at AWS Professional Services. His main focus is to help customers to modernize applications to become cloud native and to use full power of AWS platform. He is particularly interested in building distributed scalable and reliable applications using Containers and Serverless technologies.

Build incremental data pipelines to load transactional data changes using AWS DMS, Delta 2.0, and Amazon EMR Serverless

Post Syndicated from Sankar Sundaram original https://aws.amazon.com/blogs/big-data/build-incremental-data-pipelines-to-load-transactional-data-changes-using-aws-dms-delta-2-0-and-amazon-emr-serverless/

Building data lakes from continuously changing transactional data of databases and keeping data lakes up to date is a complex task and can be an operational challenge. A solution to this problem is to use AWS Database Migration Service (AWS DMS) for migrating historical and real-time transactional data into the data lake. You can then apply transformations and store data in Delta format for managing inserts, updates, and deletes.

Amazon EMR Serverless is a serverless option in Amazon EMR that makes it easy for data analysts and engineers to run open-source big data analytics frameworks without configuring, managing, and scaling clusters or servers. EMR Serverless automatically provisions and scales the compute and memory resources required by your applications, and you only pay for the resources that the applications use. EMR Serverless also provides you with more flexibility on overriding default Spark configurations, customizing EMR Serverless images, and customizing Spark driver and executor sizes to better suit specific workloads.

This post demonstrates how to implement a solution that uses AWS DMS to stream ongoing replication or change data capture (CDC) from an Amazon Aurora PostgreSQL-Compatible Edition database into Amazon Simple Storage Service (Amazon S3). We then apply transformations using Spark jobs on an EMR Serverless application and write transformed output into open-source Delta tables in Amazon S3. The Delta tables created by the EMR Serverless application are exposed through the AWS Glue Data Catalog and can be queried through Amazon Athena. Although this post uses an Aurora PostgreSQL database hosted on AWS as the data source, the solution can be extended to ingest data from any of the AWS DMS supported databases hosted on your data centers.

Solution overview

The following diagram shows the overall architecture of the solution that we implement in this post.

Architecture diagram

The solution consists of the following steps for implementing a full and incremental (CDC) data ingestion from a relational database:

  • Data storage and data generation – We create an Aurora PostgreSQL database and generate fictional trip data by running a stored procedure. The data will have attributes like trip ID (primary key), timestamp, source location, and destination location. Incremental data is generated in the PostgreSQL table by running custom SQL scripts.
  • Data ingestion – Steps 1 and 2 use AWS DMS, which connects to the source database and moves full and incremental data (CDC) to Amazon S3 in Parquet format. Let’s refer to this S3 bucket as the raw layer.
  • Data transformation – Steps 3 and 4 represent an EMR Serverless Spark application (Amazon EMR 6.9 with Apache Spark version 3.3.0) created using Amazon EMR Studio. The script reads input data from the S3 raw bucket, and then invokes Delta Lake’s MERGE statements to merge the data with the target S3 bucket (curated layer). The script also creates and updates a manifest file on Amazon S3 every time the job is run to enable data access from Athena and Amazon Redshift Spectrum.
  • Data access – The EMR Serverless job has code snippets that create a Delta table in the AWS Glue Data Catalog in Step 5. Steps 6 and 7 describe using Athena and Redshift Spectrum to query data from the Delta tables using standard SQL through the AWS Glue Data Catalog.
  • Data pipeline – Step 8 describes the process for triggering the data pipeline in a periodic manner through Airflow operators using Amazon Managed Workflows for Apache Airflow (Amazon MWAA). Refer to Submitting EMR Serverless jobs from Airflow for additional details. In this post, AWS DMS has been configured to replicate data from Amazon Aurora PostgreSQL-Compatible Edition into an S3 bucket with hourly partitions. The Airflow DAG can be configured to call an EMR Serverless job to process the past X hours of data based on specific project requirements. Implementation of the Airflow setup is not explored within the scope of this post.

The architecture has the following major features:

  • Reliability – The end-to-end architecture is made resilient with the Multi-AZ feature of EMR Serverless and using Multi-AZ deployments for AWS DMS and Amazon Aurora PostgreSQL-Compatible Edition. When you submit jobs to an EMR Serverless application, those jobs are automatically distributed to different Availability Zones in the Region. A job is run in a single Availability Zone to avoid performance implications of network traffic across Availability Zones. In case an Availability Zone is impaired, a job submitted to your EMR Serverless application is automatically run in a different (healthy) Availability Zone. When using resources in a private VPC, EMR Serverless recommends that you specify the private VPC configuration for multiple Availability Zones so that EMR Serverless can automatically select a healthy Availability Zone.
  • Cost optimization – When you run Spark or Hive applications using EMR Serverless, you pay for the amount of vCPU, memory, and storage resources consumed by your applications, leading to optimal utilization of resources. There is no separate charge for Amazon Elastic Compute Cloud (Amazon EC2) instances or Amazon Elastic Block Store (Amazon EBS) volumes. For additional details on cost, refer to Amazon EMR Serverless cost estimator.
  • Performance efficiency – You can run analytics workloads at any scale with automatic on-demand scaling that resizes resources in seconds to meet changing data volumes and processing requirements. EMR Serverless includes the Amazon EMR performance-optimized runtime for Apache Spark and Hive. The Amazon EMR runtime for Spark is 100% API-compatible with OSS Spark and is over 3.5 times as fast as the standard open-source, so your jobs run faster and incur less compute costs. With fast and fine-grained scaling in EMR Serverless, if a pipeline runs daily and needs to process 1 GB of data one day and 100 GB of data another day, EMR Serverless automatically scales to handle that load.
  • Monitoring – EMR Serverless sends metrics to Amazon CloudWatch at the application and job level every 1 minute. You can set up a single-view dashboard in CloudWatch to visualize application-level and job-level metrics using an AWS CloudFormation template provided on the EMR Serverless CloudWatch Dashboard GitHub repository. Also, EMR Serverless can store application logs in a managed storage, Amazon S3, or both based on your configuration settings. After you submit a job to an EMR Serverless application, you can view the real-time Spark UI or the Hive Tez UI for the running job from the EMR Studio console or request a secure URL using the GetDashboardForJobRun API. For completed jobs, you can view the Spark History Server or the Persistent Hive Tez UI from the EMR Studio console.

The following steps are performed to implement this solution:

  1. Connect to the Aurora PostgreSQL instance and generate a sample dataset.
    • Set up a data pipeline for loading data from Amazon Aurora PostgreSQL-Compatible Edition into Delta Lake on Amazon S3 and query using Athena:
    • Start the AWS DMS task to perform full table load and capture ongoing replication to the S3 raw layer.
    • Run the EMR Serverless Spark application to load data into Delta Lake.
    • Query the Delta tables (native tables) through Athena.
  2. Run the data pipeline to capture incremental data changes into Delta Lake:
    • Generate an incremental (CDC) dataset and insert it into the Aurora PostgreSQL database.
    • Run the EMR Serverless Spark application to merge CDC data in the S3 curated layer (incremental load).
    • Query the Delta Lake tables through Athena to validate the merged data.

Prerequisites

We use a CloudFormation template to provision the AWS resources required for the solution. The CloudFormation template requires you to select an EC2 key pair. This key is configured on an EC2 instance that lives in the public subnet. We use this EC2 instance to connect to the Aurora PostgreSQL instance that lives in the private subnet. Make sure you have a key in the Region where you deploy the template. If you don’t have one, you can create a new key pair.

To walk through this post, we use Delta Lake version > 2.0.0, which is supported in Apache Spark 3.2.x. Choose the Delta Lake version compatible with your Spark version by visiting the Delta Lake releases page. We use an EMR Serverless application with version emr-6.9.0, which supports Spark version 3.3.0.

Deploy your resources

To provision the resources needed for the solution, complete the following steps:

  1. Choose Launch Stack:

  1. For Stack name, enter emr-serverless-deltalake-blog.
  2. For DatabaseUserName, enter the user name for logging in to Amazon Aurora PostgreSQL-Compatible Edition. Keep the default value if you don’t want to change it.
  3. For DatabasePassword, enter the password for logging in to Amazon Aurora PostgreSQL-Compatible Edition.
  4. For ClientIPCIDR, enter the IP address of your SQL client that will be used to connect to the EC2 instance. We use this EC2 instance to connect to the Aurora PostgreSQL database.
  5. For KeyName, enter the key pair to be used in your EC2 instance. This EC2 instance will be used as a proxy to connect from your SQL client to the Aurora PostgreSQL source database.
  6. For EC2ImageId, PrivateSubnet1CIDR, PrivateSubnet2CIDR, PublicSubnetCIDR, and VpcCIDR, keep the default values or choose appropriate values for the VPC and EC2 image for your specific environment.
  7. Choose Next.
  8. Choose Next again.
  9. On the review page, select I acknowledge that AWS CloudFormation might create IAM resources with custom names.
  10. Choose Create stack.

After the CloudFormation template is complete and the resources are created, the Outputs tab shows the information shown in the following screenshot.

The CloudFormation template creates all the resources needed for the solution workflow:

  • S3 raw and curated buckets
  • Aurora PostgreSQL database
  • AWS DMS migration task, replication instance, and other resources
  • EC2 instance for running data ingestion scripts
  • AWS Identity and Access Management (IAM) roles and policies needed to perform the necessary activities as part of this solution
  • VPC, subnets, security groups, and relevant network components
  • AWS Lambda functions that perform setup activities required for this workflow
  • Additional components needed for running the EMR Serverless workflow

You can find the PySpark script in the raw S3 bucket on the Amazon S3 console as shown in the following screenshot. The bucket will have the naming structure <CloudFormation template name>-rawS3bucket-<random string>. Make a note of the S3 path to the emr_delta_cdc.py script; you need this information while submitting the Spark job via the EMR Serverless application.

The preceding task for creating the resources via CloudFormation assumes that AWS Lake Formation is not enabled in the Region (which we enable later in this post). If you already have Lake Formation enabled in the Region, make sure the IAM user or role used in the CloudFormation template has the necessary permissions to create a database in the AWS Glue Data Catalog.

Connect to the Aurora PostgreSQL instance and generate a sample dataset

Connect to the Aurora PostgreSQL endpoint using your preferred client. For this post, we use the PSQL command line tool. Note that the IP address of the client machine from which you’re connecting to the database must be updated in the Aurora PostgreSQL security group. This is done by the CloudFormation template based on the input parameter value for ClientIPCIDR. If you’re accessing the database from another machine, update the security group accordingly.

  1. Connect to your EC2 instance from the command line using the public DNS of the EC2 instance from the CloudFormation template output.
  2. Log in to the EC2 instance and connect to the Aurora PostgreSQL instance using the following commands (the Aurora PostgreSQL endpoint is available on the Outputs tab of the CloudFormation stack):
    psql -h << Aurora PostgreSQL endpoint >> -p 5432 -U <<username>> -d emrdelta_source_db

  1. Run the following commands to create a schema and table for the fictional trip dataset:
    create schema delta_emr_source;
    
    create table delta_emr_source.travel_details (trip_id int PRIMARY KEY,tstamp timestamp, route_id varchar(2),destination varchar(50),source_location varchar(50));

  1. Create the following stored procedure to generate the records for the trip dataset and insert the records into the table.
    create or replace procedure delta_emr_source.insert_records(records int)
    language plpgsql
    as $$
    declare
    max_trip_id integer;
    begin
    --get max trip_id
    select coalesce(max(trip_id),1) into max_trip_id from delta_emr_source.travel_details;
    
    --insert records
    for i in max_trip_id+1..max_trip_id+records loop
    INSERT INTO delta_emr_source.travel_details (trip_id, tstamp, route_id,destination,source_location) values (i, current_timestamp, chr(65 + (i % 10)),(array['Seattle', 'New York', 'New Jersey', 'Los Angeles', 'Las Vegas',
    'Tucson', 'Washington DC', 'Philadelphia', 'Miami', 'San Francisco'])[(floor(random() * 10))+1],(array['Seattle', 'New York', 'New Jersey', 'Los Angeles', 'Las Vegas',
    'Tucson', 'Washington DC', 'Philadelphia', 'Miami', 'San Francisco'])[(floor(random() * 10))+1]);
    end loop;
    
    commit;
    
    raise notice 'Inserted record count - %', records;
    end; $$;

  2. Call the preceding stored procedure to insert 20,000 records into the Aurora PostgreSQL database:
    call delta_emr_source.insert_records(20000);

  3. After the stored procedure is complete, verify that the records have been inserted successfully:
    select count(*) from delta_emr_source.travel_details;
    

Set up a data pipeline for loading data into Delta tables on Amazon S3 and query using Athena

In this section, we walk through the steps to set up a data pipeline that loads data from Amazon Aurora PostgreSQL-Compatible Edition into Delta tables on Amazon S3 and then query the data using Athena.

Start the AWS DMS task to perform full table load to the S3 raw layer

To perform the full table load, complete the following steps:

  1. On the AWS DMS console, choose Database migration tasks in the navigation pane.
  2. Select the task that was created by the CloudFormation template (emrdelta-postgres-s3-migration).
  3. On the Actions menu, choose Restart/Resume.

The task starts the full load and ongoing replication of data from the source database to Amazon S3.

  1. Wait for the job to complete.

You can validate that the data has been migrated successfully checking the Load state column for the AWS DMS task.

  1. Navigate to the S3 bucket created from the CloudFormation template to store raw data from AWS DMS.The bucket will have the naming structure <CloudFormation template name>-rawS3bucket-<random string>.
  2. Navigate to the folder delta_emr_source/travel_details in the raw S3 bucket. You can verify the S3 folder has Parquet data populated from the AWS DMS task.

Run the EMR Serverless Spark application to load data into Delta tables

We use EMR Studio to manage and submit jobs in an EMR Serverless application.

  1. Launch EMR Studio and create an EMR Serverless application.
  2. For Name, enter emr-delta-blog.
  3. For Type, choose Spark.
  4. For Release version, choose your release version.
  5. For Architecture, select x86_64.
  6. For Application setup options, select Choose default settings.

  1. Choose Create application and verify that the EMR application has been created successfully on the Amazon EMR console.

  1. Choose emr_delta_blog and then choose Start application. You can verify that the EMR application has started successfully on the Amazon EMR console, as shown in the following screenshot.


The application will move to Stopped status after a period of inactivity. When you submit the job to the application, it will start again and start the job. This provides cost savings because the jobs are run on demand as opposed to maintaining a running EMR cluster.

  1. While the application is in Started status, choose Submit job to submit the job to the application.

Create a new job in the Job details page

  1. For Name, enter emr-delta-load-job.
  2. For Runtime role, choose emrserverless-execution-role.
  3. For S3 URI, enter the S3 (raw bucket) path where the script emr_delta_cdc.py is uploaded.
  4. For Script arguments, enter ["I","delta_emr_source","9999-12-31-01","travel_details","route_id"].

The script arguments provide the following details to the EMR Serverless application:

  • I – The first argument represents the data load type. The allowed values are I for full load and U for incremental data load.
  • delta_emr_source – The second argument represents the source database schema from which data is being migrated through the AWS DMS task.
  • 9999-12-31-01 – The third argument represents the partition from which data needs to be loaded in an incremental fashion. This argument is used only during CDC data load; for full load, we have provided a default value (9999-12-31-01).
  • travel_details – The fourth argument represents the source database table from which data is being migrated through the AWS DMS task. Use a semicolon as a delimiter when entering multiple tables.
  • route_id – The fifth argument represents the partition keys on which the table data should be partitioned when stored in the S3 curated bucket. Use a semicolon as a delimiter when entering comma-separated partition keys for multiple tables.

With arguments, you can group a set of tables and submit the job to an EMR Serverless application. You can provide multiple table names separated by semicolons and enter the partition keys for those tables also separated by semicolon. If a particular table doesn’t have a partition key, simply enter a semicolon alone. The number of semicolon-separated values should match the table and partition key arguments for the script to run successfully.

Also, if you want to capture additional tables as part of an existing EMR Serverless job, you need to create a new EMR Serverless job to capture full load separately (set the first argument as I along with the new table names) and then change the argument list of the existing EMR Serverless job to add those new tables to capture incremental data load going forward.

EMR Serverless version 6.9.0 comes pre-installed with Delta version 2.1.0. Refer to About Amazon EMR Releases for more details about pre-installed libraries and applications for a specific Amazon EMR release. Before this, we have to upload the Delta JAR files to an S3 bucket in your account and provide the JAR file path in the application configurations using the spark.jars option. In this walkthrough, we create an EMR Serverless 6.9.0 application and use the pre-installed Delta jars from Amazon EMR.

  1. Under Spark properties, choose Edit in text and enter the following configurations:
--conf spark.jars=/usr/share/aws/delta/lib/delta-core.jar,/usr/share/aws/delta/lib/delta-storage.jar --conf spark.sql.extensions=io.delta.sql.DeltaSparkSessionExtension --conf spark.sql.catalog.spark_catalog=org.apache.spark.sql.delta.catalog.DeltaCatalog --conf spark.submit.pyFiles=/usr/share/aws/delta/lib/delta-core.jar --conf spark.hadoop.hive.metastore.client.factory.class=com.amazonaws.glue.catalog.metastore.AWSGlueDataCatalogHiveClientFactory

If you want to use a different version of Delta JAR files, you can replace the S3 path of the JAR files in these configuration options.

  1. Leave the rest of the configurations at their default and choose Submit job.
  2. Wait for the job to complete successfully. You can verify this on the EMR Serverless console.

  1. Additionally, go to the S3 location (the curated bucket created by AWS CloudFormation) and verify that the Delta files are created along with the manifest file.

  1. Select a job run and then choose Spark History Server (Completed jobs) on the View Application UIs menu.


You can now use the Spark History Server UI to navigate to various tabs and analyze the job run in a detailed manner. For Spark error and output logs, you can navigate to the Executors tab and explore the driver or executor logs as required. This can help you to debug the job in case of failures by looking at the Spark logs.You can also choose Spark UI (Running jobs) to track the progress of the EMR Serverless Spark jobs while they are running.

The data load script is the same for initial and incremental data load because it can handle both the workflows through script arguments:

from pyspark.sql import SparkSession
from datetime import datetime
from pyspark.sql.functions import *
from pyspark.sql.window import Window
import boto3
import sys
from delta import *

# S3 bucket location, auto-populated for this post. Replace for other jobs
raw_bucket="<<raw_bucket_name>>"
curated_bucket= "<<curated_bucket_name>>"

spark = (
SparkSession.builder.appName("SparkSQL")
.config("spark.sql.extensions", "io.delta.sql.DeltaSparkSessionExtension")
.config("spark.sql.catalog.spark_catalog", "org.apache.spark.sql.delta.catalog.DeltaCatalog")
.enableHiveSupport()
.getOrCreate()
)

#Check for argument list and if it doesn't match the expected argument count, exit the program
if len(sys.argv) != 6:
print("This script requires 5 arguments for successful execution - Load_type,database_schema,CDC_path,source_table,Partition_keys")
print(sys.argv)
sys.exit(0)

s3 = boto3.client('s3')

# Split table names into a list if there are more than one table seperated by semicolon
tables = sys.argv[4].split(";")

schema = sys.argv[2]
load_type = sys.argv[1]
cdc_partition = sys.argv[3]
deltaHivePath = "s3://" + curated_bucket + "/" + schema + "/"
columns_to_drop = ["Op","schema_name", "table_name", "update_ts_dms", "tstamp"]
db_name = "emrserverless_delta"

# Split table partition keys into a list if there are more than one table separated by semicolon
partition_keys = sys.argv[5].split(";")
# Exit if length of table names and partition keys are different to ensure data is provided for all tables.
if len(tables)!=len(partition_keys):
print("Please enter partition keys for all tables. if partition key is not present enter empty semicolon - T1_PK;;T3PK")
sys.exit(0)


i = 0
while i < len(tables):
table = tables[i]
partition_key = partition_keys[i].split(",")
print(partition_key)
if load_type == 'I':
print("Moving to Full-load logic for the table", table)

# Read the data from the raw bucket
source_df1 = spark.read.format("parquet").load(
"s3://" + raw_bucket + "/" + schema + "/" + table + "/")

# There is no target table in Delta format. Loading for the first time
# The following code segment populates Delta table in S3 and also
# updated the Glue catalog for querying with Athena.
additional_options = {"path": deltaHivePath + table + "/"}
if columns_to_drop is not None and columns_to_drop != '':
source_df1 = source_df1.drop(*columns_to_drop)

#Check for presence of partition key and before writing data to Curated bucket
if partition_key[0]:
source_df1.write.mode("append")\
.format("delta")\
.partitionBy(*partition_key)\
.options(**additional_options)\
.saveAsTable(db_name + ".spark_" + table)
else:
source_df1.write.mode("append")\
.format("delta")\
.options(**additional_options)\
.saveAsTable(db_name + ".spark_" + table)

# Generate symlink for Amazon Redshift Spectrum to read data
deltaTable = DeltaTable.forPath(spark, deltaHivePath + table + "/")
deltaTable.generate("symlink_format_manifest")

else:
print("Moving to upsert logic, Reading data from partition - ",cdc_partition)
# The below logic will verify if the CDC path has data before proceeding with
# incremental load. if CDC path is not available for a specific table the load
# process is skipped to avoid spark read error.
resp = s3.list_objects_v2(
Bucket=raw_bucket,
Prefix=schema +"/" +table +"/" +cdc_partition,
Delimiter='/',
MaxKeys=1)
if 'CommonPrefixes' in resp:
update_df = spark.read.format("parquet").load(
"s3://" + raw_bucket + "/" + schema + "/" + table + "/" + cdc_partition + "/")

# Get recent record for each primary key to update the recent transaction to the Delta table
# This step is needed to de-dup transactions like inserts and deletes within the same batch
sort_order = Window.partitionBy(
col('trip_id')).orderBy(
col('update_ts_dms').desc())
update_df = update_df.withColumn("rec_val", row_number().over(
sort_order)).filter("rec_val=1").drop("rec_val")

# upsert script using Merge operation. The below script updates/inserts data
# on all columns. In case you need to insert/update specific columns
# use whenNotMatchedInsert/whenMatchedUpdate functions and parameterize the input for each table
deltaTable = DeltaTable.forPath(spark, deltaHivePath + table + "/")
deltaTable.alias('trg') \
.merge(update_df.alias('src'),'trg.trip_id = src.trip_id')\
.whenNotMatchedInsertAll(condition="src.Op = 'I'") \
.whenMatchedUpdateAll(condition="src.Op='U'") \
.whenMatchedDelete(condition="src.Op = 'D'") \
.execute()

# Generate symlink for Amazon Redshift Spectrum to read data
deltaTable.generate("symlink_format_manifest")
else:
print("The path is empty for table -", table)
i = i + 1
print("The Job has completed execution...")

Monitor EMR Serverless application using CloudWatch dashboards

We can optionally monitor the EMR Serverless application using CloudWatch dashboards by installing the CloudFormation template from the EMR Serverless CloudWatch Dashboard GitHub repository.Follow the instructions on the Getting started section on the GitHub repository and deploy the CloudFormation template in your account.

You need to provide the EMR Serverless application ID as a parameter while deploying the CloudFormation stack, which can be obtained on the EMR Studio Applications page as shown in the following screenshot.

After the CloudFormation template is successfully deployed, navigate to the CloudWatch console to see a custom dashboard created for the EMR Serverless application ID that was provided to the CloudFormation template.

Choose the dashboard to see the different metrics for the EMR Serverless application in a single dashboard view.

You can see the available workers (one driver and two executors that were pre-initialized in the default configuration) and also the spike under successful job count that indicates the initial data load job that was completed successfully.

You could also monitor the CPU, memory, and storage allocated for the application, driver, and executor nodes separately.

The following image shows application metrics for three workers with 12 vCPUs (both driver and executor initialized with 4 vCPUs) and also the memory and storage usage. You can monitor the metrics from this dashboard and pre-initialize your application capacity that suits your specific workloads.

We can see the number of executors that were utilized for this job execution from the executor metrics section within the CloudWatch dashboard. We have used two executors and a driver for running this job.

Query the Delta tables through Athena

Previously, Delta tables were accessed through Athena by generating the manifest files (which maintain the list of data files to read for querying a Delta table). With the newly launched support in Athena for reading native Delta tables, it’s no longer required to generate and update manifest files. The Athena SQL engine version 3 can directly query native Delta tables. If you’re using an older engine version, change the engine version.

Navigate to the Athena console and start querying the data. Run a SELECT query and fetch the first 10 records to verify the data:

SELECT * FROM "AwsDataCatalog"."emrserverless_delta"."spark_travel_details" limit 10;

The table (native Delta table) has been created and updated to the AWS Glue Data Catalog from the EMR Serverless application code. You can successfully query and explore the data through Athena or Spark applications, but the schema definitions for individual columns aren’t updated in Data Catalog with this approach.

The following screenshot shows the Delta table created through code has a single array column. Athena supports reading native Delta tables and therefore we can read the data successfully even though the Data Catalog shows only a single array column.

If you need the individual column-level metadata to be available in the Data Catalog, run an AWS Glue crawler periodically to keep the AWS Glue metadata updated. For more information, refer to Introducing native Delta Lake table support with AWS Glue crawlers.

Run the data pipeline to load incremental data changes into the Delta tables

In this section, we walk through the steps to run the data pipeline.

Generate an incremental (CDC) dataset and insert it into the Aurora PostgreSQL database

  1. Log in to the EC2 instance via SSH and using the PSQL CLI, run the following SQL commands to generate CDC data on the source database:

update delta_emr_source.travel_details set destination='Tucson' where destination='Miami';
call delta_emr_source.insert_records(200);
delete from delta_emr_source.travel_details where destination='Los Angeles';

  1. Navigate to the AWS DMS console and verify whether the incremental records are populated to the S3 raw bucket by the replication task.

You can also verify in the S3 raw bucket location that the files are created under hourly partitioned folders.

Run the EMR Serverless Spark application to merge CDC data in the S3 curated layer (incremental load)

After the AWS DMS task has successfully loaded the incremental data, submit the Spark job on the EMR Serverless application to load the incremental data (CDC) with the following script arguments:

["U", "delta_emr_source", "2022-10-25-21", "travel_details","route_id"]

The partition path given here as 2022-10-25-21 should be changed as applicable in your use case. We use an example use case where the EMR Serverless job runs every hour, and the input data folder is partitioned on an hourly basis from AWS DMS. You can choose an appropriate partitioning strategy on the S3 raw bucket for your use case.

  1. Under Spark properties, choose Edit in text and enter the following configurations:
--conf spark.jars=/usr/share/aws/delta/lib/delta-core.jar,/usr/share/aws/delta/lib/delta-storage.jar --conf spark.sql.extensions=io.delta.sql.DeltaSparkSessionExtension --conf spark.sql.catalog.spark_catalog=org.apache.spark.sql.delta.catalog.DeltaCatalog --conf spark.submit.pyFiles=/usr/share/aws/delta/lib/delta-core.jar --conf spark.hadoop.hive.metastore.client.factory.class=com.amazonaws.glue.catalog.metastore.AWSGlueDataCatalogHiveClientFactory

  1. When the job is successful, verify in Amazon S3 that more files are created in the _delta_log folder, capturing the changes from the current run.

Query the Delta tables through Athena to validate the merged data

Go to the Athena console to query the data and validate count to ensure that the table contains the most recent data:

SELECT destination, count(*) FROM "AwsDataCatalog"."emrserverless_delta"."spark_travel_details" group by destination;

If you also want to query this data from Amazon Redshift, you can create external tables in Redshift Spectrum for Delta tables. For more information, refer to Creating external tables for data managed in Delta Lake. Redshift Spectrum currently supports querying Delta tables through the manifest file option. A Delta table manifest contains a list of files that make up a consistent snapshot of the Delta table. The code snippet given in this post updates the manifest files every time new data is loaded in the Delta tables to ensure only the latest data is read from the Delta tables.

Clean up

To avoid incurring ongoing charges, clean up your infrastructure by deleting the stack from the AWS CloudFormation console. Delete the EMR Serverless application and any other resources you created during this exercise.

Conclusion

In this post, we demonstrated how to create a transactional data lake with Delta table format using EMR Serverless and AWS DMS. With the flexibility provided by EMR Serverless, you can use the latest version of open-source Delta framework on EMR Serverless (with the latest version of Spark) in order to support a wider range of transactional data lake needs based on various use cases.

Now you can build a transactional data lake for your organization with Delta table format and access data using Athena and Redshift Spectrum for various analytical workloads. You could use this high-level architecture for any other use cases where you need to use the latest version of Spark on EMR Serverless.


About the Authors

Sankar Sundaram is a Data Lab Architect at AWS, where he helps customers build and modernize data architectures and help them build secure, scalable, and performant data lake, database, and data warehouse solutions.

Monjumi Sarma is a Data Lab Solutions Architect at AWS. She helps customers architect data analytics solutions, which gives them an accelerated path towards modernization initiatives.
How to send web push notifications using Amazon Pinpoint

Post Syndicated from arrohan original https://aws.amazon.com/blogs/messaging-and-targeting/how-to-send-web-push-notifications-using-amazon-pinpoint/

How to send push notifications on any website using AWS messaging tools

Web Push Notifications (also known as browser push notifications) are messages from a website you receive in your browser. These messages are intended to be rich, contextual, timely, personalized and best used to engage, re-engage, and retain website visitors. For instance, as a website owner you could use web push notifications to notify users about sales, important updates or new content on your website.

How are web push notifications different from native app push notifications?

Push notifications are short messages that are displayed directly on the user’s screen sent via mobile applications, providing timely information and messages like order status, promotions, or relevant news in the application.

Web push notifications are simply push notifications sent via web browsers (the browser application on the device), and they work across platforms – Desktop, mobile and tablet.  They are a newer channel than push notifications, and have now become a part of the modern marketing strategy alongside native app push notifications, emails and SMS.

In the case of mobile apps, the user must install the application to receive push notifications. In the case of web push, there is no need to download any software—it just takes one click on your website.

Why are Web Push Notifications useful?

Let’s consider a real-world example. Suppose you are an e-commerce website where customers can purchase products. Once, the purchase has been made, customers would be interested in getting real time updates of where the package is in transit, when is it likely to be delivered, a confirmation that the shipment has been delivered and so on. Web push notifications can be an excellent way of providing such updates. Accessing email on mobile devices is often unwieldy, SMS messages cannot support images and are constrained in length (also they typically they cost more money to send!). Push notifications are perfect for such a use case. Till now, the major constraint was that it would require users to install your app on their device. Web push notifications gives website owners and customers the power of push notifications without any need for driving app installs.

Marketers in a variety of sectors like travel, publishing, restaurant & delivery, finance and insurance can use push notifications to improve their down-to-funnel conversions.  From new content alerts to limited-time promotions to upcoming events, push messages are short, crisp and drive engagement, conversion, and retention. A short search on the AWS blogs website gives us a number of examples of businesses who have created value for their customers with the help of push notifications. Some of the key advantages of web push notifications are:

  • Easy opt in model: Unlike other marketing channels like email or SMS, web push notifications offer users a seamless opt-in experience ― Users simply select `Allow’ on a browser permission prompt. Users do not have to worry about sharing their personal data, like their name, email, or phone number nor do they have to go to the play store/app store and install an app on their device.
  • Increased Engagement:  Push notifications appear on a user’s desktop or mobile screen and are quick to grab attention. Since push messages are real time and have high visibility – they typically enjoy higher “Click Through Rate (CTR)” as compared to other channels like SMS or email.
  • Reach users even when they are not on your website: Web Push Notifications from your website are delivered and shown to the customer even if the user is visiting some other site or on some other app. In this respect (and most others), it is quite similar to app push notifications. Even if subscribers were offline when you sent your push campaign, they will get the push message delivered to them the next time they come online.
  • No need for users to install native apps: One of the most compelling reason for installing mobile apps, is because users could stay updated with the latest and the greatest – thanks to app push notifications. The additional cost of going to the play store/app store and installing the app is something which would often discourage users. This is especially true for countries and regions where users are still on lower end phones with limited storage space. Users would often have to uninstall apps (which might include yours too) that they do not use frequently in order to make space for other stuff.
  • Makes websites richer and more memorable: If you ask a room of developers what mobile device features are missing from the web, push notifications are always high on the list. This is no longer the case since browsers are increasingly adding support for web push notifications and this has offered website owners a powerful cross platform (Desktop & Mobile, Android & iOS) alternative as against developing and maintaining different native apps for different platforms. Web push notifications even appear quite similar to native mobile push on most smartphones.
  • Lower Cost: Unlike channels like SMS, sending web push notifications is absolutely free as browsers themselves offer support for it by adhering to the web push protocol. The only costs incurred will be that of sending push notifications as per the Pinpoint pricing policy.
  • Popular browsers support web push: Google Chrome, Firefox, Opera, Edge support web push on both Mobile and Desktop. What’s more the support for web push is continuously getting better. Refer to this link for the latest support status matrix across browsers and form factors.

What is Amazon Pinpoint?

Amazon Pinpoint is an AWS service that provides scalable, targeted multichannel communications. Amazon Pinpoint enables companies to send messages to customers through SMS, push notifications, in-app notifications, email, and voice channels. To learn more about Amazon Pinpoint, visit the website and documentation.

Web Push support on Firebase Cloud Messaging (FCM):

Firebase uses cloud services for its notification services on Android, iOS & Web. Firebase Cloud Messaging or FCM run on basic principles of tokens, which is uniquely generated for each device & later used for sending messages to respective devices. There are two key advantages of using FCM for sending web push notifications:

  • Abstracts away the complexity of onboarding to the web push protocol for push messages: Sending web push notifications directly without any third party in between requires your website to add support for the web push protocol. Adherence to the web push protocol requires website owners to perform some steps specific to wpn like adding VAPID headers and payload encryption of push messages. This would be additional work for website owners, especially for those businesses which are already onboarded to FCM for sending native app push notifications. FCM server side apis for sending web push notifications work pretty much the same way as they work for native apps. They abstract away the additional complexity of sending web push messages.
  • Send push notifications from Amazon Pinpoint via FCM: Amazon Pinpoint already supports integration with FCM, refer to documentation. Similar to how we add a FCM project in Pinpoint to send push messages to native android apps, in this blog post we will see how a similar integration can be leveraged to send web push notifications.

Advantages of sending Web Push Notifications with Amazon Pinpoint:

Now at this point, you might be thinking, Web push notifications can go a long way towards delighting customers and FCM already abstracts the complexities of sending web push. So why do I need Amazon Pinpoint?

Well, integration with Amazon Pinpoint offers a number of advantages. Here are a few:

  • Map FCM tokens to actual users and web app ‘installs’: FCM would give you tokens for each user on your website who subscribes for web push. Roughly speaking, an FCM token for each web app install with permissions to send push messages. To be able to send messages to these users we would need to store the FCM tokens for each user/web app install/browser instance. Amazon Pinpoint treats each browser instance as an endpoint and enables you to save the push tokens in the same way in which we would store native push tokens/mobile numbers/email addresses, i.e., as a primary identifier for that endpoint. This enables us to send messages to Pinpoint endpoints without caring about the underlying complexity of storing and managing push tokens.
  • Intelligently send web push, map user attributes to push tokens: Along with the push token, each pinpoint endpoint can also store other attributes like device characteristics, user Id and user attributes. This helps us to create dynamic and complex segments which can be used to send targeted web push notifications.
  • It is essentially the same as sending android native push: Create an FCM project, create FCM tokens, Create Pinpoint endpoints with the tokens, send push campaigns to those endpoints. Swap out native android code with service workers, JavaScript on the client and you get web push. It really is that simple.
  • Web push, native push, SMS or emails. One stop shop for reaching out to users on all channels: Pinpoint becomes your single backend for reaching out to users across multiple channels. For app users, send them app push, for users who prefer the web, you have web push.
  • Leverage Pinpoint features like Campaign Management, Events, Analytics and Segments: Read up about Amazon Pinpoint. It has a lot of great features which can help you better engage your users.

In this blog we will see how to send web push notifications using Amazon Pinpoint on a website built using AWS Amplify.

 Overview of solution

Enable web push by using FCM as an intermediary service and Pinpoint as an app server (map FCM tokens to actual users) and a push campaign management tool. Integrate web push protocol, FCM and Amazon Pinpoint.

Overview of how to setup Web Push - registering the customer

Overview of how to setup Web Push - sending push notifications

Walkthrough

In this blog post, we will create a simple demo website using Amplify which can be used to create web push subscriptions and also receive web push messages. We will integrate this website with FCM js sdk and Amazon Pinpoint to store the FCM push tokens on Pinpoint. Later we will see how to send web push notifications using Amazon Pinpoint with FCM acting as an intermediary.

The above can be broken down into the below simple and independent steps:

  • Create a project on FCM.
  • Generate web push notifications server keys on FCM.
  • Create a simple web app (website) using Amplify
  • Create an Amazon Pinpoint project. This is a one-line command which will be done as part of Amplify web app setup.
  • Make your amplify website web push capable. In this step we will also integrate with the FCM sdk for web push.
  • Configure the Pinpoint project and integrate it with FCM. It just involves adding the FCM server key to Pinpoint.
  • Go to the Amazon Pinpoint console and send a test web push message from your website. And we are done!

You can see checkout my demo website here.

The source code for this demo website (and the blog) is available here.

Prerequisites – Essentials

For this walkthrough, you should have the following prerequisites:

Prerequisites – Recommended

In addition to the necessary prerequisites mentioned above, I would highly recommend readers to go through the below in order to derive maximum value from this blog post.

  • Web Push fundamentals: Some basic reading up on web push notifications and going through a couple of relevant code samples. It is not compulsory to implement and understand everything, but it would be beneficial to have an elementary understanding of service workers, permissions, push subscriptions and notifications apis.
    • Introduction: Some of the sections are a bit detailed and complex, you need not go through all the sections completely at once. However, at least go through the overview and the how push works sections carefully.
    • Simple Code demo with explanations to help you get started.
  • FCM client-side code : You need not go through the send Message sections since we will not directly use FCM apis or the console. Instead, we will use the Pinpoint console to manage our push campaigns.
  • Building web apps with amplify: By the end of the tutorial, you should get clarity on how to build and host web apps using amplify. It will also help you become familiar with the amplify cli tool.
  • Read up on Amazon Pinpoint.

Setting up the demo web app

Let’s deploy the demo web app using AWS Amplify to see how all the parts come together.

Clone the code for the sample web app

git clone ssh://git.amazon.com/pkg/ArrohanWebPushPoc (branch: PinpointBlog) <github_link>

Create an FCM account and a project on the FCM developer console, on the FCM project add web push as a channel

It is possible that Firebase may change the UI of the console in the future so the given screenshots may not be exactly reflective of the UI, but the broad steps would remain the same.

  • Under “Engage”  click on ‘Cloud Messaging Tab’.  The page url should typically be of the form: https://console.firebase.google.com/u/0/project/<name_of_your_project>/notification.

Setting up web push - Getting the firebase push config

  • Under the option “Add an app to get started”, Click on the “web/javascript” (the one with the </> symbol) app.
  • Once you have created the project,  go to project settings. Click on General Tab. Replace the values in firebaseConfig main.js with the actual values for your project.

Setting up web push - Copying the firebase push config

Setting up web push - Code pointer for the firebase push config

Generate a public-private key pair for the FCM cloud messaging project

  • Under project settings, switch to the cloud messaging tab. Click generate key pair under web push certificates to generate a public-private key pair.

Setting up web push - Generate a public-private vapid key pair

  • Replace the <YOUR PUBLIC KEY> in the file main.js in the source code with the vapid public key you generated in the previous step.

Setting up web push - Copying the FCM server key

  • Note the Server key, you will need it during pinpoint project setup.

Setup an Amplify web app and integrate with pinpoint

  • Clone the code in the given repo, replace your FCM config and keys. Run npm install.
    • In case you face build errors due to package versions getting outdated (firebase, especially gets updated often, sometimes with breaking changes), please update the dependencies to the latest version. This post offers an easy way to identify outdated dependencies and update them.
  • Setup an Amplify web app. Note, for the purpose of this demo, you just need to setup a simple static website. Simply run amplify init. Enter the required details, the default config should work fine.

Setting up the example app for web push using Amazon Pinpoint

  • Create a pinpoint project and integrate with our web app through amplify cli:
    • Create a pinpoint project: Run amplify add analytics. Choose Amazon Pinpoint as the analytics provider and accept all defaults.
    • Please note when you add “analytics” to the project you will get a prompt which says something like – “Apps need authorization to send analytics events. Do you want to allow guests and unauthenticated users to send analytics events? (We recommend you allow this when getting started)” – Please accept and answer Yes when you get this.
    • Push to AWS: Run amplify push. A configuration file (aws-exports.js) will be added to the source directory. Notice, we are calling this file from our main.js file.

Setting up the example app for web push using Amazon Pinpoint

Pinpoint Project setup

  • Get the Server key of the FCM project you created earlier.

Setting up web push - Add FCM key to Pinpoint console

Run the web app and subscribe for push notifications

  • Run npm start, our web app will be running on http://localhost:8080/index.html
  • Click on enable push messages and click allow/accept on the browser permission prompt which follows. Once it is enabled, you will see a FCM token on the page, copy the token.

How the example app looks

Send a web push notification from the Amazon Pinpoint console

  • Open the pinpoint project you created in the previous step on the Pinpoint console. Click on your project and then go to test messaging. The process is exactly the same as the one for native apps described here. Under “destination type” select “Device Tokens” and paste the FCM token you copied in the previous step.

Sending a web push from the Pinpoint console

  • Fill in title, body and optionally URL (“Go to a URL” under “Actions”). Click on Send Message, you should get a push message on your browser.

How an example web push notification looks like on Desktop

Next steps

  • Host your app. Simply run amplify add hosting followed by amplify publish. Remember that for web push (service workers) to work, your site should be https.

Deploying the example app for web push using AWS Amplify

  • Create segments, campaigns and journeys on pinpoint and try sending web push messages through them.

Code Walkthrough

  • Gitfarmlink: https://code.amazon.com/packages/ArrohanWebPushPoc/trees/heads/PinpointBlog
  • File wise description:
    • package.json: Simple npm config file. It includes the list of dependencies and their versions used by our web app. For our use case, all we need is webpack and AWS Amplify.
    • package-lock.json: Auto generated config file generated by npm after resolving modules and package.json.
    • aws-exports.js: Auto generated configuration file created by Amplify cli. This file contains the configuration and endpoint metadata used to link your front end to your backend services. It will be structured similar to the sample config file.
    • webpack.config.js: Simple webpack configuration file
    • src: The folder which contains the source code for our web app. It contains:
      • service-worker.js: The service worker that we register for our website which is used to display push notifications. In the service worker we parse the notification payload sent through pinpoint and call the notification apis to display push notification with the appropriate fields.
      • index.html: The website html.
      • main.js: The heart of the web app. It does permission handling, push subscription management and communicates with FCM and Amazon Pinpoint.
      • images/icon-192×192.png: static icon that we display on our push messages. This would essentially be your website logo.

Conclusion

This small demo shows how we can send web push notifications using Amazon Pinpoint. As next steps to come up with an actual production ready solution, you can look into the following:

  • Develop deeper understanding and expertise on web push
  • Richer and smarter push notification: Add big images, action buttons, replace notifications using tags (for example, sports score updates) and explore other features in the show notifications api.
  • Smart push notifications: add custom business logic in the payload. Hint: use the “body” (“pinpoint.notification.body“) field on the pinpoint console to send a custom json string.
  • Driving more subscriptions: Leverage Amplify Analytics to track how users interact with the push subscribe UI. Think of where and how you might ask users to subscribe to drive maximum engagement.
  • Easy unsubscribe: Allow users an easy option to disable push notifications without having to block you from browser settings. Also, make sure that you are disabling that endpoint on pinpoint. Hint: use the updateEndpoint api and pass optOut from ‘ALL’ as the argument.
  • Targeted and personalised push notifications: Leverage Pinpoint segments to send users push notifications according to their interests and requirements. Hint: add user data to endpoints and use it to filter and create targeted segments.
  • Campaign management: Leverage pinpoint features like segments, analytics, campaigns, journeys and more!

Project Cleanup

In this section we will quickly go over the steps to delete the resources we created for this demo to make sure that we do not incur any charges.

  • Cleaning up all AWS resources including the Amazon Pinpoint project, S3 buckets for hosting (and any other resources you may have added): Simply run amplify delete from the project directory on your command line.
  • Cleaning up the FCM Project: Refer to the FCM support page for the steps to delete a project – https://support.google.com/firebase/answer/9137886 .
    • Open the project settings page: The URL will be of the form https://console.firebase.google.com/u/0/project/<your_project_identifier>/settings/general
    • Click on the delete project button at the bottom of the page.

Access Amazon Athena in your applications using the WebSocket API

Post Syndicated from Abhi Sodhani original https://aws.amazon.com/blogs/big-data/access-amazon-athena-in-your-applications-using-the-websocket-api/

Modern applications are built with modular independent components or microservices that rely on an API framework to communicate with services. Many organizations are building data lakes to store and analyze large volumes of structured, semi-structured, and unstructured data. In addition, many teams are moving towards a data mesh architecture, which requires them to expose their data sets as easily consumable data products. To accomplish this on AWS, organizations use Amazon Simple Storage Service (Amazon S3) to provide cheap and reliable object storage to house their datasets. To enable interactive querying and analyzing their data in place using familiar SQL syntax, many teams are turning to Amazon Athena. Athena is an interactive query service that is used by modern applications to query large volumes of data on an S3 data lake using standard SQL.

When working with SQL databases, application developers and business analysts are most familiar with simple permissions management and synchronous query-response protocols—if a user has permissions to submit a query, they do so and receive the results from the server when the query is complete. Directly accessing Athena APIs, for example when integrating with a custom web application, requires an AWS Identity and Access Management (IAM) role for the applications, and requires you to build a custom process to poll for query completion asynchronously. The IAM role needs access to run Athena API calls, as well as S3 permissions to retrieve the Athena output stored on Amazon S3. Polling for Athena query completion when performed at several intervals could result in increased latency from the client perspective.

In this post, we present a solution that can integrate with your front-end application to query data from Amazon S3 using an Athena synchronous API invocation. With this solution, you can add a layer of abstraction to your application on direct Athena API calls and promote the access using the WebSocket API developed with Amazon API Gateway. The query results are returned back to the application as Amazon S3 presigned URLs.

Overview of solution

For illustration purposes, this post builds a COVID-19 data lake with a WebSocket API to handle Athena queries. Your application can invoke the WebSocket API to pull the data from Amazon S3 using an Athena SQL query, and the WebSocket API returns the JSON response with the presigned Amazon S3 URL. The application needs to parse the JSON message to read the presigned URL, download the data to local, and report the data back to the front end.

We use AWS Step Functions to poll the Athena query run. When the query is complete, Step Functions invokes an AWS Lambda function to generate the presigned URL and send the request back to the application.

The application doesn’t require direct access to Athena, just access to invoke the API. When using this solution, you should secure the API following AWS guidelines. For more information, refer to Controlling and managing access to a WebSocket API in API Gateway.

The following diagram summarizes the architecture, key components, and interactions in the solution.

Architecture diagram for the Athena WebSocket API. The user connects to the API through API Gateway. API Gateway uses Lambda and DynamoDB to store session data. SQL queries are routed to Amazon Athena and a Step Function polls for query status and returns the results back to the user.

The application is composed of the WebSocket API in API Gateway, which handles the connectivity between the client and Athena. A client application using the framework can submit the Athena SQL query and get back the presigned URL containing the query results data. The workflow includes the following steps:

  1. The application invokes the WebSocket API connection.
  2. A Lambda function is invoked to initiate the connection. The connection ID is stored in an Amazon DynamoDB
  3. When the client application is connected, it can invoke the runquery action, which invokes the RunQuery Lambda function.
  4. The function first runs the Athena query.
  5. When the query is started, the function checks the status and uses Step Functions to track the query progress.
  6. Step Functions invokes the third Lambda function to read the processed Athena results and get the presigned S3 URL. Failed messages are routed to an Amazon Simple Notification Service (Amazon SNS) topic, which you can subscribe to.
  7. The presigned URL is returned to the client application.
  8. The connection is closed using the OnDisconnect function.

The RunQuery Lambda function runs the Athena query using the start_query_execution request:

def run_query(client, query):
    """This function executes and sends the query request to Athena."""
    response = client.start_query_execution(
        QueryString=query,
        QueryExecutionContext={
            'Database': params['Database']
        },
        ResultConfiguration={
            'OutputLocation': f's3://{params["BucketName"]}/{params["OutputDir"]}/'
        },
        WorkGroup=params["WorkGroup"]
    )
    return response

The Amazon S3 presigned URL is generated by invoking the generate_presigned_url request with the bucket and key information that hosts the Athena results. The code hard codes the presigner expiration to 120 seconds, which is configurable in the function input parameter PreSignerExpireSeconds. See the following code:

def signed_get_url(event):
    s3 = boto3.client('s3', region_name=params['Region'], config=Config(signature_version='s3v4'))
    # User provided body with object info
    bodyData = json.loads(event['body'])
    try:
        url = s3.generate_presigned_url(
            ClientMethod='get_object',
            Params={
                'Bucket': params['BucketName'],
                'Key': bodyData["ObjectName"]
            },
            ExpiresIn=int(params['PreSignerExpireSeconds'])
        )
        body = {'PreSignedUrl': url, 'ExpiresIn': params['PreSignerExpireSeconds']}
        response = {
            'statusCode': 200,
			'body': json.dumps(body),
            'headers': cors.global_returns["Allow Origin Header"]
        }
        logger.info(f"[MESSAGE] Response for PreSignedURL: {response}")
    except Exception as e:
        logger.exception(f"[MESSAGE] Unable to generate URL: {str(e)}")
        response = {
            'statusCode': 502,
            'body': 'Unable to generate PreSignedUrl',
            'headers': cors.global_returns["Allow Origin Header"]
        }
    return response

Prerequisites

This post assumes you have the following:

  • Access to an AWS account
  • Permissions to create an AWS CloudFormation stack
  • Permissions to create the following resources:
    • AWS Glue catalog databases and tables
    • API Gateway
    • Lambda function
    • IAM roles
    • Step Functions state machine
    • SNS topic
    • DynamoDB table

Enable the WebSocket API

To enable the WebSocket API of API Gateway, complete the following steps:

  1. Configure the Athena dataset.

To make the data from the AWS COVID-19 data lake available in the Data Catalog in your AWS account, create a CloudFormation stack using the following template. If you’re signed in to your AWS account, the following page fills out most of the stack creation form for you. All you need to do is choose Create stack. For instructions on creating a CloudFormation stack, see Getting started with AWS CloudFormation.

You can also use an existing Athena database to query, in which case you need to update the stack parameters.

  1. Sign in to the Athena console.

If this is the first time you’re using Athena, you must specify a query result location on Amazon S3. For more information about querying and accessing the data from Athena, see A public data lake for analysis of COVID-19 data.

  1. Configure the WebSocket framework using the following page, which deploys the API infrastructure using AWS Serverless Application Model (AWS SAM).
  2. Update the parameters pBucketName with the S3 bucket (in the us-east-2 region) that stores the Athena results and also update the database if you want to query an existing database.
  3. Select the check box to acknowledge creation of IAM roles and choose Deploy.

At a high level, these are the primary resources deployed by the application template:

  • An API Gateway with routes to the connect, disconnect, and query Lambda functions. Note that the API Gateway deployed with this sample doesn’t implement authentication and authorization. We recommend that you implement authentication and authorization before deploying into a production environment. Refer to Controlling and managing access to a WebSocket API in API Gateway to understand how to implement these security controls.
  • A DynamoDB table for tracking client connections.
  • Lambda functions to manage connection states using DynamoDB.
  • A Lambda function to run the query and start the step function. The function includes an associated IAM role and policies with permissions to Step Functions, the AWS Glue Data Catalog, Athena, AWS Key Management Service (AWS KMS), and Amazon S3. Note that the Lambda execution role gives read access to the Data Catalog and S3 bucket that you specify in the deployment parameters. We recommend that you don’t include a catalog that contains sensitive data without first understanding the impacts and implementing additional security controls.
  • A Lambda function with associated permissions to poll for the query results and return the presigned URL to the client.
  • A Step Functions state machine with associated permissions to run the polling Lambda function and send API notifications using Amazon SNS.

Test the setup

To test the WebSocket API, you can use wscat, an open-source command line tool.

  1. Install NPM.
  2. Install wscat:
$ npm install -g wscat
  1. On the console, connect to your published API endpoint by running the following command. The full URI to use can be found on the AWS CloudFormation console by finding the WebSocketURI output in the serverlessrepo-aws-app-athena-websocket-integration stack that was deployed by the AWS SAM application you deployed previously.
$ wscat -c wss://{YOUR-API-ID}.execute-api.{YOUR-REGION}.amazonaws.com/{STAGE}
  1. To test the runquery function, send a JSON message like the following example. This triggers the state machine to run your SQL query using Athena and, using Lambda, return an S3 presigned URL to your client, which you can access to download the query results. Note that the API accepts any valid Athena query. Additional query validation could be added to the internal Lambda function if desired.
$ wscat -c wss://{YOUR-API-ID}.execute-api.{YOUR-REGION}.amazonaws.com/{STAGE}
Connected (press CTRL+C to quit)
> {"action":"runquery", "data":"SELECT * FROM \"covid-19\".country_codes limit 5"}
< {"pre-signed-url": "https://xxx-s3.amazonaws.com/athena_api_access_results/xxxxx.csv?"}
  1. Copy the value for pre-signed-url and enter it into your browser window to access the results.

The presigned URL provides you temporary credentials to download the query results. For more information, refer to Using presigned URLs. This process can be integrated into a front-end web application to automatically download and display the results of the query.

Clean up

To avoid incurring ongoing charges, delete the resources you provisioned by deleting the CloudFormation stacks CovidLakeStacks and serverlessrepo-AthenaWebSocketIntegration via the AWS CloudFormation console. For detailed instructions, refer to the cleanup sections in the starter kit README files in the GitHub repo.

Conclusion

In this post, we showed how to integrate your application with Athena using the WebSocket API. We have included a GitHub repo for you to understand the code and modify it per your application requirements, to get the full benefits of the solution. We encourage you to further explore the features of the API Gateway WebSocket API to add in security using authorizers, view live invocations using dashboards, and expand the framework for more routes on action request.

Let’s stay in touch via the GitHub repo.


About the Authors

Abhi Sodhani is a Sr. AI/ML Solutions Architect at AWS. He helps customers with a wide range of solutions, including machine leaning, artificial intelligence, data lakes, data warehousing, and data visualization. Outside of work, he is passionate about books, yoga, and travel.
Robin Zimmerman's HeadshotRobin Zimmerman is a Data and ML Engineer with AWS Professional Services. He works with AWS enterprise customers to develop systems to extract value from large volumes of data using AWS data, analytics, and machine learning services. When he’s not working, you’ll probably find him in the mountains—rock climbing, skiing, mountain biking, or out on whatever other adventure he can dream up.

Use Apache Iceberg in a data lake to support incremental data processing

Post Syndicated from Flora Wu original https://aws.amazon.com/blogs/big-data/use-apache-iceberg-in-a-data-lake-to-support-incremental-data-processing/

Apache Iceberg is an open table format for very large analytic datasets, which captures metadata information on the state of datasets as they evolve and change over time. It adds tables to compute engines including Spark, Trino, PrestoDB, Flink, and Hive using a high-performance table format that works just like a SQL table. Iceberg has become very popular for its support for ACID transactions in data lakes and features like schema and partition evolution, time travel, and rollback.

Apache Iceberg integration is supported by AWS analytics services including Amazon EMR, Amazon Athena, and AWS Glue. Amazon EMR can provision clusters with Spark, Hive, Trino, and Flink that can run Iceberg. Starting with Amazon EMR version 6.5.0, you can use Iceberg with your EMR cluster without requiring a bootstrap action. In early 2022, AWS announced general availability of Athena ACID transactions, powered by Apache Iceberg. The recently released Athena query engine version 3 provides better integration with the Iceberg table format. AWS Glue 3.0 and later supports the Apache Iceberg framework for data lakes.

In this post, we discuss what customers want in modern data lakes and how Apache Iceberg helps address customer needs. Then we walk through a solution to build a high-performance and evolving Iceberg data lake on Amazon Simple Storage Service (Amazon S3) and process incremental data by running insert, update, and delete SQL statements. Finally, we show you how to performance tune the process to improve read and write performance.

How Apache Iceberg addresses what customers want in modern data lakes

More and more customers are building data lakes, with structured and unstructured data, to support many users, applications, and analytics tools. There is an increased need for data lakes to support database like features such as ACID transactions, record-level updates and deletes, time travel, and rollback. Apache Iceberg is designed to support these features on cost-effective petabyte-scale data lakes on Amazon S3.

Apache Iceberg addresses customer needs by capturing rich metadata information about the dataset at the time the individual data files are created. There are three layers in the architecture of an Iceberg table: the Iceberg catalog, the metadata layer, and the data layer, as depicted in the following figure (source).

The Iceberg catalog stores the metadata pointer to the current table metadata file. When a select query is reading an Iceberg table, the query engine first goes to the Iceberg catalog, then retrieves the location of the current metadata file. Whenever there is an update to the Iceberg table, a new snapshot of the table is created, and the metadata pointer points to the current table metadata file.

The following is an example Iceberg catalog with AWS Glue implementation. You can see the database name, the location (S3 path) of the Iceberg table, and the metadata location.

The metadata layer has three types of files: the metadata file, manifest list, and manifest file in a hierarchy. At the top of the hierarchy is the metadata file, which stores information about the table’s schema, partition information, and snapshots. The snapshot points to the manifest list. The manifest list has the information about each manifest file that makes up the snapshot, such as location of the manifest file, the partitions it belongs to, and the lower and upper bounds for partition columns for the data files it tracks. The manifest file tracks data files as well as additional details about each file, such as the file format. All three files work in a hierarchy to track the snapshots, schema, partitioning, properties, and data files in an Iceberg table.

The data layer has the individual data files of the Iceberg table. Iceberg supports a wide range of file formats including Parquet, ORC, and Avro. Because the Iceberg table tracks the individual data files instead of only pointing to the partition location with data files, it isolates the writing operations from reading operations. You can write the data files at any time, but only commit the change explicitly, which creates a new version of the snapshot and metadata files.

Solution overview

In this post, we walk you through a solution to build a high-performing Apache Iceberg data lake on Amazon S3; process incremental data with insert, update, and delete SQL statements; and tune the Iceberg table to improve read and write performance. The following diagram illustrates the solution architecture.

To demonstrate this solution, we use the Amazon Customer Reviews dataset in an S3 bucket (s3://amazon-reviews-pds/parquet/). In real use case, it would be raw data stored in your S3 bucket. We can check the data size with the following code in the AWS Command Line Interface (AWS CLI):

//Run this AWS CLI command to check the data size
aws s3 ls --summarize --human-readable --recursive s3://amazon-reviews-pds/parquet

The total object count is 430, and total size is 47.4 GiB.

To set up and test this solution, we complete the following high-level steps:

  1. Set up an S3 bucket in the curated zone to store converted data in Iceberg table format.
  2. Launch an EMR cluster with appropriate configurations for Apache Iceberg.
  3. Create a notebook in EMR Studio.
  4. Configure the Spark session for Apache Iceberg.
  5. Convert data to Iceberg table format and move data to the curated zone.
  6. Run insert, update, and delete queries in Athena to process incremental data.
  7. Carry out performance tuning.

Prerequisites

To follow along with this walkthrough, you must have an AWS account with an AWS Identity and Access Management (IAM) role that has sufficient access to provision the required resources.

Set up the S3 bucket for Iceberg data in the curated zone in your data lake

Choose the Region in which you want to create the S3 bucket and provide a unique name:

s3://iceberg-curated-blog-data

Launch an EMR cluster to run Iceberg jobs using Spark

You can create an EMR cluster from the AWS Management Console, Amazon EMR CLI, or AWS Cloud Development Kit (AWS CDK). For this post, we walk you through how to create an EMR cluster from the console.

  1. On the Amazon EMR console, choose Create cluster.
  2. Choose Advanced options.
  3. For Software Configuration, choose the latest Amazon EMR release. As of January 2023, the latest release is 6.9.0. Iceberg requires release 6.5.0 and above.
  4. Select JupyterEnterpriseGateway and Spark as the software to install.
  5. For Edit software settings, select Enter configuration and enter [{"classification":"iceberg-defaults","properties":{"iceberg.enabled":true}}].
  6. Leave other settings at their default and choose Next.
  7. For Hardware, use the default setting.
  8. Choose Next.
  9. For Cluster name, enter a name. We use iceberg-blog-cluster.
  10. Leave the remaining settings unchanged and choose Next.
  11. Choose Create cluster.

Create a notebook in EMR Studio

We now walk you through how to create a notebook in EMR Studio from the console.

  1. On the IAM console, create an EMR Studio service role.
  2. On the Amazon EMR console, choose EMR Studio.
  3. Choose Get started.

The Get started page appears in a new tab.

  1. Choose Create Studio in the new tab.
  2. Enter a name. We use iceberg-studio.
  3. Choose the same VPC and subnet as those for the EMR cluster, and the default security group.
  4. Choose AWS Identity and Access Management (IAM) for authentication, and choose the EMR Studio service role you just created.
  5. Choose an S3 path for Workspaces backup.
  6. Choose Create Studio.
  7. After the Studio is created, choose the Studio access URL.
  8. On the EMR Studio dashboard, choose Create workspace.
  9. Enter a name for your Workspace. We use iceberg-workspace.
  10. Expand Advanced configuration and choose Attach Workspace to an EMR cluster.
  11. Choose the EMR cluster you created earlier.
  12. Choose Create Workspace.
  13. Choose the Workspace name to open a new tab.

In the navigation pane, there is a notebook that has the same name as the Workspace. In our case, it is iceberg-workspace.

  1. Open the notebook.
  2. When prompted to choose a kernel, choose Spark.

Configure a Spark session for Apache Iceberg

Use the following code, providing your own S3 bucket name:

%%configure -f
{
"conf": {
"spark.sql.catalog.demo": "org.apache.iceberg.spark.SparkCatalog",
"spark.sql.catalog.demo.catalog-impl": "org.apache.iceberg.aws.glue.GlueCatalog",
"spark.sql.catalog.demo.warehouse": "s3://iceberg-curated-blog-data",
"spark.sql.extensions":"org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions",
"spark.sql.catalog.demo.io-impl":"org.apache.iceberg.aws.s3.S3FileIO"
}
}

This sets the following Spark session configurations:

  • spark.sql.catalog.demo – Registers a Spark catalog named demo, which uses the Iceberg Spark catalog plugin.
  • spark.sql.catalog.demo.catalog-impl – The demo Spark catalog uses AWS Glue as the physical catalog to store Iceberg database and table information.
  • spark.sql.catalog.demo.warehouse – The demo Spark catalog stores all Iceberg metadata and data files under the root path defined by this property: s3://iceberg-curated-blog-data.
  • spark.sql.extensions – Adds support to Iceberg Spark SQL extensions, which allows you to run Iceberg Spark procedures and some Iceberg-only SQL commands (you use this in a later step).
  • spark.sql.catalog.demo.io-impl – Iceberg allows users to write data to Amazon S3 through S3FileIO. The AWS Glue Data Catalog by default uses this FileIO, and other catalogs can load this FileIO using the io-impl catalog property.

Convert data to Iceberg table format

You can use either Spark on Amazon EMR or Athena to load the Iceberg table. In the EMR Studio Workspace notebook Spark session, run the following commands to load the data:

// create a database in AWS Glue named reviews if not exist
spark.sql("CREATE DATABASE IF NOT EXISTS demo.reviews")

// load reviews - this load all the parquet files
val reviews_all_location = "s3://amazon-reviews-pds/parquet/"
val reviews_all = spark.read.parquet(reviews_all_location)

// write reviews data to an Iceberg v2 table
reviews_all.writeTo("demo.reviews.all_reviews").tableProperty("format-version", "2").createOrReplace()

After you run the code, you should find two prefixes created in your data warehouse S3 path (s3://iceberg-curated-blog-data/reviews.db/all_reviews): data and metadata.

Process incremental data using insert, update, and delete SQL statements in Athena

Athena is a serverless query engine that you can use to perform read, write, update, and optimization tasks against Iceberg tables. To demonstrate how the Apache Iceberg data lake format supports incremental data ingestion, we run insert, update, and delete SQL statements on the data lake.

Navigate to the Athena console and choose Query editor. If this is your first time using the Athena query editor, you need to configure the query result location to be the S3 bucket you created earlier. You should be able to see that the table reviews.all_reviews is available for querying. Run the following query to verify that you have loaded the Iceberg table successfully:

select * from reviews.all_reviews limit 5;

Process incremental data by running insert, update, and delete SQL statements:

//Example update statement
update reviews.all_reviews set star_rating=5 where product_category = 'Watches' and star_rating=4

//Example delete statement
delete from reviews.all_reviews where product_category = 'Watches' and star_rating=1

Performance tuning

In this section, we walk through different ways to improve Apache Iceberg read and write performance.

Configure Apache Iceberg table properties

Apache Iceberg is a table format, and it supports table properties to configure table behavior such as read, write, and catalog. You can improve the read and write performance on Iceberg tables by adjusting the table properties.

For example, if you notice that you write too many small files for an Iceberg table, you can config the write file size to write fewer but bigger size files, to help improve query performance.

Property Default Description
write.target-file-size-bytes 536870912 (512 MB) Controls the size of files generated to target about this many bytes

Use the following code to alter the table format:

//Example code to alter table format in EMR Studio Workspace notebook
spark.sql("ALTER TABLE demo.reviews.all_reviews 
SET TBLPROPERTIES ('write_target_data_file_size_bytes'='536870912')")

Partitioning and sorting

To make a query run fast, the less data read the better. Iceberg takes advantage of the rich metadata it captures at write time and facilitates techniques such as scan planning, partitioning, pruning, and column-level stats such as min/max values to skip data files that don’t have match records. We walk you through how query scan planning and partitioning work in Iceberg and how we use them to improve query performance.

Query scan planning

For a given query, the first step in a query engine is scan planning, which is the process to find the files in a table needed for a query. Planning in an Iceberg table is very efficient, because Iceberg’s rich metadata can be used to prune metadata files that aren’t needed, in addition to filtering data files that don’t contain matching data. In our tests, we observed Athena scanned 50% or less data for a given query on an Iceberg table compared to original data before conversion to Iceberg format.

There are two types of filtering:

  • Metadata filtering – Iceberg uses two levels of metadata to track the files in a snapshot: the manifest list and manifest files. It first uses the manifest list, which acts as an index of the manifest files. During planning, Iceberg filters manifests using the partition value range in the manifest list without reading all the manifest files. Then it uses selected manifest files to get data files.
  • Data filtering – After selecting the list of manifest files, Iceberg uses the partition data and column-level stats for each data file stored in manifest files to filter data files. During planning, query predicates are converted to predicates on the partition data and applied first to filter data files. Then, the column stats like column-level value counts, null counts, lower bounds, and upper bounds are used to filter out data files that can’t match the query predicate. By using upper and lower bounds to filter data files at planning time, Iceberg greatly improves query performance.

Partitioning and sorting

Partitioning is a way to group records with the same key column values together in writing. The benefit of partitioning is faster queries that access only part of the data, as explained earlier in query scan planning: data filtering. Iceberg makes partitioning simple by supporting hidden partitioning, in the way that Iceberg produces partition values by taking a column value and optionally transforming it.

In our use case, we first run the following query on the Iceberg table not partitioned. Then we partition the Iceberg table by the category of the reviews, which will be used in the query WHERE condition to filter out records. With partitioning, the query could scan much less data. See the following code:

//Example code in EMR Studio Workspace notebook to create an Iceberg table all_reviews_partitioned partitioned by product_category
reviews_all.writeTo("demo.reviews.all_reviews_partitioned").tableProperty("format-version", "2").partitionedBy($"product_category").createOrReplace()

Run the following select statement on the non-partitioned all_reviews table vs. the partitioned table to see the performance difference:

//Run this query on all_reviews table and the partitioned table for performance testing
select marketplace,customer_id, review_id,product_id,product_title,star_rating from reviews.all_reviews where product_category = 'Watches' and review_date between date('2005-01-01') and date('2005-03-31')

//Run the same select query on partitioned dataset
select marketplace,customer_id, review_id,product_id,product_title,star_rating from reviews.all_reviews_partitioned where product_category = 'Watches' and review_date between date('2005-01-01') and date('2005-03-31')

The following table shows the performance improvement of data partitioning, with about 50% performance improvement and 70% less data scanned.

Dataset Name Non-Partitioned Dataset Partitioned Dataset
Runtime (seconds) 8.20 4.25
Data Scanned (MB) 131.55 33.79

Note that the runtime is the average runtime with multiple runs in our test.

We saw good performance improvement after partitioning. However, this can be further improved by using column-level stats from Iceberg manifest files. In order to use the column-level stats effectively, you want to further sort your records based on the query patterns. Sorting the whole dataset using the columns that are often used in queries will reorder the data in such a way that each data file ends up with a unique range of values for the specific columns. If these columns are used in the query condition, it allows query engines to further skip data files, thereby enabling even faster queries.

Copy-on-write vs. read-on-merge

When implementing update and delete on Iceberg tables in the data lake, there are two approaches defined by the Iceberg table properties:

  • Copy-on-write – With this approach, when there are changes to the Iceberg table, either updates or deletes, the data files associated with the impacted records will be duplicated and updated. The records will be either updated or deleted from the duplicated data files. A new snapshot of the Iceberg table will be created and pointing to the newer version of data files. This makes the overall writes slower. There might be situations that concurrent writes are needed with conflicts so retry has to happen, which increases the write time even more. On the other hand, when reading the data, there is no extra process needed. The query will retrieve data from the latest version of data files.
  • Merge-on-read – With this approach, when there are updates or deletes on the Iceberg table, the existing data files will not be rewritten; instead new delete files will be created to track the changes. For deletes, a new delete file will be created with the deleted records. When reading the Iceberg table, the delete file will be applied to the retrieved data to filter out the delete records. For updates, a new delete file will be created to mark the updated records as deleted. Then a new file will be created for those records but with updated values. When reading the Iceberg table, both the delete and new files will be applied to the retrieved data to reflect the latest changes and produce the correct results. So, for any subsequent queries, an extra step to merge the data files with the delete and new files will happen, which will usually increase the query time. On the other hand, the writes might be faster because there is no need to rewrite the existing data files.

To test the impact of the two approaches, you can run the following code to set the Iceberg table properties:

//Run code to alter Iceberg table property to set copy-on-write and merge-on-read in EMR Studio Workspace notebook
spark.sql(“ALTER TABLE demo.reviews.all_reviews 
SET TBLPROPERTIES (‘write.delete.mode’=’copy-on-write’,’write.update.mode’=’copy-on-write’)”)

Run the update, delete, and select SQL statements in Athena to show the runtime difference for copy-on-write vs. merge-on-read:

//Example update statement
update reviews.all_reviews set star_rating=5 where product_category = ‘Watches’ and star_rating=4

//Example delete statement
delete from reviews.all_reviews where product_category = ‘Watches’ and star_rating=1

//Example select statement
select marketplace,customer_id, review_id,product_id,product_title,star_rating from reviews.all_reviews where product_category = ‘Watches’ and review_date between date(‘2005-01-01’) and date(‘2005-03-31’)

The following table summarizes the query runtimes.

Query Copy-on-Write Merge-on-Read
UPDATE DELETE SELECT UPDATE DELETE SELECT
Runtime (seconds) 66.251 116.174 97.75 10.788 54.941 113.44
Data scanned (MB) 494.06 3.07 137.16 494.06 3.07 137.16

Note that the runtime is the average runtime with multiple runs in our test.

As our test results show, there are always trade-offs in the two approaches. Which approach to use depends on your use cases. In summary, the considerations come down to latency on the read vs. write. You can reference the following table and make the right choice.

. Copy-on-Write Merge-on-Read
Pros Faster reads Faster writes
Cons Expensive writes Higher latency on reads
When to use Good for frequent reads, infrequent updates and deletes or large batch updates Good for tables with frequent updates and deletes

Data compaction

If your data file size is small, you might end up with thousands or millions of files in an Iceberg table. This dramatically increases the I/O operation and slows down the queries. Furthermore, Iceberg tracks each data file in a dataset. More data files lead to more metadata. This in turn increases the overhead and I/O operation on reading metadata files. In order to improve the query performance, it’s recommended to compact small data files to larger data files.

When updating and deleting records in Iceberg table, if the read-on-merge approach is used, you might end up with many small deletes or new data files. Running compaction will combine all these files and create a newer version of the data file. This eliminates the need to reconcile them during reads. It’s recommended to have regular compaction jobs to impact reads as little as possible while still maintaining faster write speed.

Run the following data compaction command, then run the select query from Athena:

//Data compaction 
optimize reviews.all_reviews REWRITE DATA USING BIN_PACK

//Run this query before and after data compaction
select marketplace,customer_id, review_id,product_id,product_title,star_rating from reviews.all_reviews where product_category = 'Watches' and review_date between date('2005-01-01') and date('2005-03-31')

The following table compares the runtime before vs. after data compaction. You can see about 40% performance improvement.

Query Before Data Compaction After Data Compaction
Runtime (seconds) 97.75 32.676 seconds
Data scanned (MB) 137.16 M 189.19 M

Note that the select queries ran on the all_reviews table after update and delete operations, before and after data compaction. The runtime is the average runtime with multiple runs in our test.

Clean up

After you follow the solution walkthrough to perform the use cases, complete the following steps to clean up your resources and avoid further costs:

  1. Drop the AWS Glue tables and database from Athena or run the following code in your notebook:
// DROP the table 
spark.sql("DROP TABLE demo.reviews.all_reviews") 
spark.sql("DROP TABLE demo.reviews.all_reviews_partitioned") 

// DROP the database 
spark.sql("DROP DATABASE demo.reviews")
  1. On the EMR Studio console, choose Workspaces in the navigation pane.
  2. Select the Workspace you created and choose Delete.
  3. On the EMR console, navigate to the Studios page.
  4. Select the Studio you created and choose Delete.
  5. On the EMR console, choose Clusters in the navigation pane.
  6. Select the cluster and choose Terminate.
  7. Delete the S3 bucket and any other resources that you created as part of the prerequisites for this post.

Conclusion

In this post, we introduced the Apache Iceberg framework and how it helps resolve some of the challenges we have in a modern data lake. Then we walked you though a solution to process incremental data in a data lake using Apache Iceberg. Finally, we had a deep dive into performance tuning to improve read and write performance for our use cases.

We hope this post provides some useful information for you to decide whether you want to adopt Apache Iceberg in your data lake solution.


About the Authors

Flora Wu is a Sr. Resident Architect at AWS Data Lab. She helps enterprise customers create data analytics strategies and build solutions to accelerate their businesses outcomes. In her spare time, she enjoys playing tennis, dancing salsa, and traveling.

Daniel Li is a Sr. Solutions Architect at Amazon Web Services. He focuses on helping customers develop, adopt, and implement cloud services and strategy. When not working, he likes spending time outdoors with his family.

Three ways to boost your email security and brand reputation with AWS

Post Syndicated from Michael Davie original https://aws.amazon.com/blogs/security/three-ways-to-boost-your-email-security-and-brand-reputation-with-aws/

If you own a domain that you use for email, you want to maintain the reputation and goodwill of your domain’s brand. Several industry-standard mechanisms can help prevent your domain from being used as part of a phishing attack. In this post, we’ll show you how to deploy three of these mechanisms, which visually authenticate emails sent from your domain to users and verify that emails are encrypted in transit. It can take as little as 15 minutes to deploy these mechanisms on Amazon Web Services (AWS), and the result can help to provide immediate and long-term improvements to your organization’s email security.

Phishing through email remains one of the most common ways that bad actors try to compromise computer systems. Incidents of phishing and related crimes far outnumber the incidents of other categories of internet crime, according to the most recent FBI Internet Crime Report. Phishing has consistently led to large annual financial losses in the US and globally.

Overview of BIMI, MTA-STS, and TLS reporting

An earlier post has covered how you can use Amazon Simple Email Service (Amazon SES) to send emails that align with best practices, including the IETF internet standards: Sender Policy Framework (SPF), DomainKeys Identified Mail (DKIM), and Domain-based Message Authentication, Reporting, and Conformance (DMARC). This post will show you how to build on this foundation and configure your domains to align with additional email security standards, including the following:

  • Brand Indicators for Message Identification (BIMI) – This standard allows you to associate a logo with your email domain, which some email clients will display to users in their inbox. Visit the BIMI Group’s Where is my BIMI Logo Displayed? webpage to see how logos are displayed in the user interfaces of BIMI-supporting mailbox providers; Figure 1 shows a mock-up of a typical layout that contains a logo.
  • Mail Transfer Agent Strict Transport Security (MTA-STS) – This standard helps ensure that email servers always use TLS encryption and certificate-based authentication when they send messages to your domain, to protect the confidentiality and integrity of email in transit.
  • SMTP TLS reporting – This reporting allows you to receive reports and monitor your domain’s TLS security posture, identify problems, and learn about attacks that might be occurring.
Figure 1: A mock-up of how BIMI enables branded logos to be displayed in email user interfaces

Figure 1: A mock-up of how BIMI enables branded logos to be displayed in email user interfaces

These three standards require your Domain Name System (DNS) to publish specific records, for example by using Amazon Route 53, that point to web pages that have additional information. You can host this information without having to maintain a web server by storing it in Amazon Simple Storage Service (Amazon S3) and delivering it through Amazon CloudFront, secured with a certificate provisioned from AWS Certificate Manager (ACM).

Note: This AWS solution works for DKIM, BIMI, and DMARC, regardless of what you use to serve the actual email for your domains, which services you use to send email, and where you host DNS. For purposes of clarity, this post assumes that you are using Route 53 for DNS. If you use a different DNS hosting provider, you will manually configure DNS records in your existing hosting provider.

Solution architecture

The architecture for this solution is depicted in Figure 2.

Figure 2: The architecture diagram showing how the solution components interact

Figure 2: The architecture diagram showing how the solution components interact

The interaction points are as follows:

  1. The web content is stored in an S3 bucket, and CloudFront has access to this bucket through an origin access identity, a mechanism of AWS Identity and Access Management (IAM).
  2. As described in more detail in the BIMI section of this blog post, the Verified Mark Certificate is obtained from a BIMI-qualified certificate authority and stored in the S3 bucket.
  3. When an external email system receives a message claiming to be from your domain, it looks up BIMI records for your domain in DNS. As depicted in the diagram, a DNS request is sent to Route 53.
  4. To retrieve the BIMI logo image and Verified Mark Certificate, the external email system will make HTTPS requests to a URL published in the BIMI DNS record. In this solution, the URL points to the CloudFront distribution, which has a TLS certificate provisioned with ACM.

A few important warnings

Email is a complex system of interoperating technologies. It is also brittle: a typo or a missing DNS record can make the difference between whether an email is delivered or not. Pay close attention to your email server and the users of your email systems when implementing the solution in this blog post. The main indicator that something is wrong is the absence of email. Instead of seeing an error in your email server’s log, users will tell you that they’re expecting to receive an email from somewhere and it’s not arriving. Or they will tell you that they sent an email, and their recipient can’t find it.

The DNS uses a lot of caching and time-out values to improve its efficiency. That makes DNS records slow and a little unpredictable as they propagate across the internet. So keep in mind that as you monitor your systems, it can be hours or even more than a day before the DNS record changes have an effect that you can detect.

This solution uses AWS Cloud Development Kit (CDK) custom resources, which are supported by AWS Lambda functions that will be created as part of the deployment. These functions are configured to use CDK-selected runtimes, which will eventually pass out of support and require you to update them.

Prerequisites

You will need permission in an AWS account to create and configure the following resources:

  • An Amazon S3 bucket to store the files and access logs
  • A CloudFront distribution to publicly deliver the files from the S3 bucket
  • A TLS certificate in ACM
  • An origin access identity in IAM that CloudFront will use to access files in Amazon S3
  • Lambda functions, IAM roles, and IAM policies created by CDK custom resources

You might also want to enable these optional services:

  • Amazon Route 53 for setting the necessary DNS records. If your domain is hosted by another DNS provider, you will set these DNS records manually.
  • Amazon SES or an Amazon WorkMail organization with a single mailbox. You can configure either service with a subdomain (for example, [email protected]) such that the existing domain is not disrupted, or you can create new email addresses by using your existing email mailbox provider.

BIMI has some additional requirements:

  • BIMI requires an email domain to have implemented a strong DMARC policy so that recipients can be confident in the authenticity of the branded logos. Your email domain must have a DMARC policy of p=quarantine or p=reject. Additionally, the domain’s policy cannot have sp=none or pct<100.

    Note: Do not adjust the DMARC policy of your domain without careful testing, because this can disrupt mail delivery.

  • You must have your brand’s logo in Scaled Vector Graphics (SVG) format that conforms to the BIMI standard. For more information, see Creating BIMI SVG Logo Files on the BIMI Group website.
  • Purchase a Verified Mark Certificate (VMC) issued by a third-party certificate authority. This certificate attests that the logo, organization, and domain are associated with each other, based on a legal trademark registration. Many email hosting providers require this additional certificate before they will show your branded logo to their users. Others do not currently support BIMI, and others might have alternative mechanisms to determine whether to show your logo. For more information about purchasing a Verified Mark Certificate, see the BIMI Group website.

    Note: If you are not ready to purchase a VMC, you can deploy this solution and validate that BIMI is correctly configured for your domain, but your branded logo will not display to recipients at major email providers.

What gets deployed in this solution?

This solution deploys the DNS records and supporting files that are required to implement BIMI, MTA-STS, and SMTP TLS reporting for an email domain. We’ll look at the deployment in more detail in the following sections.

BIMI

BIMI is described by the Internet Engineering Task Force (IETF) as follows:

Brand Indicators for Message Identification (BIMI) permits Domain Owners to coordinate with Mail User Agents (MUAs) to display brand-specific Indicators next to properly authenticated messages. There are two aspects of BIMI coordination: a scalable mechanism for Domain Owners to publish their desired Indicators, and a mechanism for Mail Transfer Agents (MTAs) to verify the authenticity of the Indicator. This document specifies how Domain Owners communicate their desired Indicators through the BIMI Assertion Record in DNS and how that record is to be interpreted by MTAs and MUAs. MUAs and mail-receiving organizations are free to define their own policies for making use of BIMI data and for Indicator display as they see fit.

If your organization has a trademark-protected logo, you can set up BIMI to have that logo displayed to recipients in their email inboxes. This can have a positive impact on your brand and indicates to end users that your email is more trustworthy. The BIMI Group shows examples of how brand logos are displayed in user inboxes, as well as a list of known email service providers that support the display of BIMI logos.

As a domain owner, you can implement BIMI by publishing the relevant DNS records and hosting the relevant files. To have your logo displayed by most email hosting providers, you will need to purchase a Verified Mark Certificate from a BIMI-qualified certificate authority.

This solution will deploy a valid BIMI record in Route 53 (or tell you what to publish in the DNS if you’re not using Route 53) and will store your provided SVG logo and Verified Mark Certificate files in Amazon S3, to be delivered through CloudFront with a valid TLS certificate from ACM.

To support BIMI, the solution makes the following changes to your resources:

  1. A DNS record of type TXT is published at the following host:
    default._bimi.<your-domain>. The value of this record is: v=BIMI1; l=<url-of-your-logo> a=<url-of-verified-mark-certificate>. The value of <your-domain> refers to the domain that is used in the From header of messages that your organization sends.
  2. The logo and optional Verified Mark Certificate are hosted publicly at the HTTPS locations defined by <url-of-your-logo> and <url-of-verified-mark-certificate>, respectively.

MTA-STS

MTA-STS is described by the IETF in RFC 8461 as follows:

SMTP (Simple Mail Transport Protocol) MTA Strict Transport Security (MTA-STS) is a mechanism enabling mail service providers to declare their ability to receive Transport Layer Security (TLS) secure SMTP connections and to specify whether sending SMTP servers should refuse to deliver to MX hosts that do not offer TLS with a trusted server certificate.

Put simply, MTA-STS helps ensure that email servers always use encryption and certificate-based authentication when sending email to your domains, so that message integrity and confidentiality are preserved while in transit across the internet. MTA-STS also helps to ensure that messages are only sent to authorized servers.

This solution will deploy a valid MTA-STS policy record in Route 53 (or tell you what value to publish in the DNS if you’re not using Route 53) and will create an MTA-STS policy document to be hosted on S3 and delivered through CloudFront with a valid TLS certificate from ACM.

To support MTA-STS, the solution makes the following changes to your resources:

  1. A DNS record of type TXT is published at the following host: _mta-sts.<your-domain>. The value of this record is: v=STSv1; id=<unique value used for cache invalidation>.
  2. The MTA-STS policy document is hosted at and obtained from the following location: https://mta-sts.<your-domain>/.well-known/mta-sts.txt.
  3. The value of <your-domain> in both cases is the domain that is used for routing inbound mail to your organization and is typically the same domain that is used in the From header of messages that your organization sends externally. Depending on the complexity of your organization, you might receive inbound mail for multiple domains, and you might choose to publish MTA-STS policies for each domain.

Is it ever bad to encrypt everything?

In the example MTA-STS policy file provided in the GitHub repository and explained later in this post, the MTA-STS policy mode is set to testing. This means that your email server is advertising its willingness to negotiate encrypted email connections, but it does not require TLS. Servers that want to send mail to you are allowed to connect and deliver mail even if there are problems in the TLS connection, as long as you’re in testing mode. You should expect reports when servers try to connect through TLS to your mail server and fail to do so.

Be fully prepared before you change the MTA-STS policy to enforce. After this policy is set to enforce, servers that follow the MTA-STS policy and that experience an enforceable TLS-related error when they try to connect to your mail server will not deliver mail to your mail server. This is a difficult situation to detect. You will simply stop receiving email from servers that comply with the policy. You might receive reports from them indicating what errors they encountered, but it is not guaranteed. Be sure that the email address you provide in SMTP TLS reporting (in the following section) is functional and monitored by people who can take action to fix issues. If you miss TLS failure reports, you probably won’t receive email. If the TLS certificate that you use on your email server expires, and your MTA-STS policy is set to enforce, this will become an urgent issue and will disrupt the flow of email until it is fixed.

SMTP TLS reporting

SMTP TLS reporting is described by the IETF in RFC 8460 as follows:

A number of protocols exist for establishing encrypted channels between SMTP Mail Transfer Agents (MTAs), including STARTTLS, DNS-Based Authentication of Named Entities (DANE) TLSA, and MTA Strict Transport Security (MTA-STS). These protocols can fail due to misconfiguration or active attack, leading to undelivered messages or delivery over unencrypted or unauthenticated channels. This document describes a reporting mechanism and format by which sending systems can share statistics and specific information about potential failures with recipient domains. Recipient domains can then use this information to both detect potential attacks and diagnose unintentional misconfigurations.

As you gain the security benefits of MTA-STS, SMTP TLS reporting will allow you to receive reports from other internet email providers. These reports contain information that is valuable when monitoring your TLS security posture, identifying problems, and learning about attacks that might be occurring.

This solution will deploy a valid SMTP TLS reporting record on Route 53 (or provide you with the value to publish in the DNS if you are not using Route 53).

To support SMTP TLS reporting, the solution makes the following changes to your resources:

  1. A DNS record of type TXT is published at the following host: _smtp._tls.<your-domain>. The value of this record is: v=TLSRPTv1; rua=mailto:<report-receiver-email-address>
  2. The value of <report-receiver-email-address> might be an address in your domain or in a third-party provider. Automated systems that process these reports must be capable of processing GZIP compressed files and parsing JSON.

Deploy the solution with the AWS CDK

In this section, you’ll learn how to deploy the solution to create the previously described AWS resources in your account.

  1. Clone the following GitHub repository:

    git clone https://github.com/aws-samples/serverless-mail
    cd serverless-mail/email-security-records

  2. Edit CONFIG.py to reflect your desired settings, as follows:
    1. If no Verified Mark Certificate is provided, set VMC_FILENAME = None.
    2. If your DNS zone is not hosted on Route 53, or if you do not want this app to manage Route 53 DNS records, set ROUTE_53_HOSTED = False. In this case, you will need to set TLS_CERTIFICATE_ARN to the Amazon Resource Name (ARN) of a certificate hosted on ACM in us-east-1. This certificate is used by CloudFront and must support two subdomains: mta-sts and your configured BIMI_ASSET_SUBDOMAIN.
  3. Finalize the preparation, as follows:
    1. Place your BIMI logo and Verified Mark Certificate files in the assets folder.
    2. Create an MTA-STS policy file at assets/.well-known/mta-sts.txt to reflect your mail exchange (MX) servers and policy requirements. An example file is provided at assets/.well-known/mta-sts.txt.example
  4. Deploy the solution, as follows:
    1. Open a terminal in the email-security-records folder.
    2. (Recommended) Create and activate a virtual environment by running the following commands.
      python3 -m venv .venv
      source .venv/bin/activate
    3. Install the Python requirements in your environment with the following command.
      pip install -r requirements.txt
    4. Assume a role in the target account that has the permissions outlined in the Prerequisites section of this post.

      Using AWS CDK version 2.17.0 or later, deploy the bootstrap in the target account by running the following command. To learn more, see Bootstrapping in the AWS CDK Developer Guide.
      cdk bootstrap

    5. Run the following command to synthesize the CloudFormation template. Review the output of this command to verify what will be deployed.
      cdk synth
    6. Run the following command to deploy the CloudFormation template. You will be prompted to accept the IAM changes that will be applied to your account.
      cdk deploy

      Note: If you use Route53, these records are created and activated in your DNS zones as soon as the CDK finishes deploying. As the records propagate through the DNS, they will gradually start affecting the email in the affected domains.

    7. If you’re not using Route53 and instead are using a third-party DNS provider, create the CNAME and TXT records as indicated. In this case, your email is not affected by this solution until you create the records in DNS.

Testing and troubleshooting

After you have deployed the CDK solution, you can test it to confirm that the DNS records and web resources are published correctly.

BIMI

  1. Query the BIMI DNS TXT record for your domain by using the dig or nslookup command in your terminal.

    dig +short TXT default._bimi.<your-domain.example>

    Verify the response. For example:

    "v=BIMI1; l=https://bimi-assets.<your-domain.example>/logo.svg"

  2. In your web browser, open the URL from that response (for example, https://bimi-assets.<your-domain.example>/logo.svg) to verify that the logo is available and that the HTTPS certificate is valid.
  3. The BIMI group provides a tool to validate your BIMI configuration. This tool will also validate your VMC if you have purchased one.

MTA-STS

  1. Query the MTA-STS DNS TXT record for your domain.

    dig +short TXT _mta-sts.<your-domain.example>

    The value of this record is as follows:

    v=STSv1; id=<unique value used for cache invalidation>

  2. You can load the MTA-STS policy document using your web browser. For example, https://mta-sts.<your-domain.example>/.well-known/mta-sts.txt
  3. You can also use third party tools to examine your MTA-STS configuration, such as MX Toolbox.

TLS reporting

  1. Query the TLS reporting DNS TXT record for your domain.

    dig +short TXT _smtp._tls.<your-domain.example>

    Verify the response. For example:

    "v=TLSRPTv1; rua=mailto:<your email address>"

  2. You can also use third party tools to examine your TLS reporting configuration, such as Easy DMARC.

Depending on which domains you communicate with on the internet, you will begin to see TLS reports arriving at the email address that you have defined in the TLS reporting DNS record. We recommend that you closely examine the TLS reports, and use automated analytical techniques over an extended period of time before changing the default testing value of your domain’s MTA-STS policy. Not every email provider will send TLS reports, but examining the reports in aggregate will give you a good perspective for making changes to your MTA-STS policy.

Cleanup

To remove the resources created by this solution:

  1. Open a terminal in the cdk-email-security-records folder.
  2. Assume a role in the target account with permission to delete resources.
  3. Run cdk destroy.

Note: The asset and log buckets are automatically emptied and deleted by the cdk destroy command.

Conclusion

When external systems send email to or receive email from your domains they will now query your new DNS records and will look up your domain’s BIMI, MTA-STS, and TLS reporting information from your new CloudFront distribution. By adopting the email domain security mechanisms outlined in this post, you can improve the overall security posture of your email environment, as well as the perception of your brand.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Michael Davie

Michael Davie

Michael is a Senior Industry Specialist with AWS Security Assurance. He works with our customers, their regulators, and AWS teams to help raise the bar on secure cloud adoption and usage. Michael has over 20 years of experience working in the defence, intelligence, and technology sectors in Canada and is a licensed professional engineer.

Jesse Thompson

Jesse Thompson

Jesse is an Email Deliverability Manager with the Amazon Simple Email Service team. His background is in enterprise IT development and operations, with a focus on email abuse mitigation and encouragement of authenticity practices with open standard protocols. Jesse’s favorite activity outside of technology is recreational curling.

Build a semantic search engine for tabular columns with Transformers and Amazon OpenSearch Service

Post Syndicated from Kachi Odoemene original https://aws.amazon.com/blogs/big-data/build-a-semantic-search-engine-for-tabular-columns-with-transformers-and-amazon-opensearch-service/

Finding similar columns in a data lake has important applications in data cleaning and annotation, schema matching, data discovery, and analytics across multiple data sources. The inability to accurately find and analyze data from disparate sources represents a potential efficiency killer for everyone from data scientists, medical researchers, academics, to financial and government analysts.

Conventional solutions involve lexical keyword search or regular expression matching, which are susceptible to data quality issues such as absent column names or different column naming conventions across diverse datasets (for example, zip_code, zcode, postalcode).

In this post, we demonstrate a solution for searching for similar columns based on column name, column content, or both. The solution uses approximate nearest neighbors algorithms available in Amazon OpenSearch Service to search for semantically similar columns. To facilitate the search, we create features representations (embeddings) for individual columns in the data lake using pre-trained Transformer models from the sentence-transformers library in Amazon SageMaker. Finally, to interact with and visualize results from our solution, we build an interactive Streamlit web application running on AWS Fargate.

We include a code tutorial for you to deploy the resources to run the solution on sample data or your own data.

Solution overview

The following architecture diagram illustrates the two-stage workflow for finding semantically similar columns. The first stage runs an AWS Step Functions workflow that creates embeddings from tabular columns and builds the OpenSearch Service search index. The second stage, or the online inference stage, runs a Streamlit application through Fargate. The web application collects input search queries and retrieves from the OpenSearch Service index the approximate k-most-similar columns to the query.

Solution architecture

Figure 1. Solution architecture

The automated workflow proceeds in the following steps:

  1. The user uploads tabular datasets into an Amazon Simple Storage Service (Amazon S3) bucket, which invokes an AWS Lambda function that initiates the Step Functions workflow.
  2. The workflow begins with an AWS Glue job that converts the CSV files into Apache Parquet data format.
  3. A SageMaker Processing job creates embeddings for each column using pre-trained models or custom column embedding models. The SageMaker Processing job saves the column embeddings for each table in Amazon S3.
  4. A Lambda function creates the OpenSearch Service domain and cluster to index the column embeddings produced in the previous step.
  5. Finally, an interactive Streamlit web application is deployed with Fargate. The web application provides an interface for the user to input queries to search the OpenSearch Service domain for similar columns.

You can download the code tutorial from GitHub to try this solution on sample data or your own data. Instructions on the how to deploy the required resources for this tutorial are available on Github.

Prerequistes

To implement this solution, you need the following:

  • An AWS account.
  • Basic familiarity with AWS services such as the AWS Cloud Development Kit (AWS CDK), Lambda, OpenSearch Service, and SageMaker Processing.
  • A tabular dataset to create the search index. You can bring your own tabular data or download the sample datasets on GitHub.

Build a search index

The first stage builds the column search engine index. The following figure illustrates the Step Functions workflow that runs this stage.

Step functions workflow

Figure 2 – Step functions workflow – multiple embedding models

Datasets

In this post, we build a search index to include over 400 columns from over 25 tabular datasets. The datasets originate from the following public sources:

For the the full list of the tables included in the index, see the code tutorial on GitHub.

You can bring your own tabular dataset to augment the sample data or build your own search index. We include two Lambda functions that initiate the Step Functions workflow to build the search index for individual CSV files or a batch of CSV files, respectively.

Transform CSV to Parquet

Raw CSV files are converted to Parquet data format with AWS Glue. Parquet is a column-oriented format file format preferred in big data analytics that provides efficient compression and encoding. In our experiments, the Parquet data format offered significant reduction in storage size compared to raw CSV files. We also used Parquet as a common data format to convert other data formats (for example JSON and NDJSON) because it supports advanced nested data structures.

Create tabular column embeddings

To extract embeddings for individual table columns in the sample tabular datasets in this post, we use the following pre-trained models from the sentence-transformers library. For additional models, see Pretrained Models.

Model name Dimension Size (MB)
all-MiniLM-L6-v2 384 80
all-distilroberta-v1 768 290
average_word_embeddings_glove.6B.300d 300 420

The SageMaker Processing job runs create_embeddings.py(code) for a single model. For extracting embeddings from multiple models, the workflow runs parallel SageMaker Processing jobs as shown in the Step Functions workflow. We use the model to create two sets of embeddings:

  • column_name_embeddings – Embeddings of column names (headers)
  • column_content_embeddings – Average embedding of all the rows in the column

For more information about the column embedding process, see the code tutorial on GitHub.

An alternative to the SageMaker Processing step is to create a SageMaker batch transform to get column embeddings on large datasets. This would require deploying the model to a SageMaker endpoint. For more information, see Use Batch Transform.

Index embeddings with OpenSearch Service

In the final step of this stage, a Lambda function adds the column embeddings to a OpenSearch Service approximate k-Nearest-Neighbor (kNN) search index. Each model is assigned its own search index. For more information about the approximate kNN search index parameters, see k-NN.

Online inference and semantic search with a web app

The second stage of the workflow runs a Streamlit web application where you can provide inputs and search for semantically similar columns indexed in OpenSearch Service. The application layer uses an Application Load Balancer, Fargate, and Lambda. The application infrastructure is automatically deployed as part of the solution.

The application allows you to provide an input and search for semantically similar column names, column content, or both. Additionally, you can select the embedding model and number of nearest neighbors to return from the search. The application receives inputs, embeds the input with the specified model, and uses kNN search in OpenSearch Service to search indexed column embeddings and find the most similar columns to the given input. The search results displayed include the table names, column names, and similarity scores for the columns identified, as well as the locations of the data in Amazon S3 for further exploration.

The following figure shows an example of the web application. In this example, we searched for columns in our data lake that have similar Column Names (payload type) to district (payload). The application used all-MiniLM-L6-v2 as the embedding model and returned 10 (k) nearest neighbors from our OpenSearch Service index.

The application returned transit_district, city, borough, and location as the four most similar columns based on the data indexed in OpenSearch Service. This example demonstrates the ability of the search approach to identify semantically similar columns across datasets.

Web application user interface

Figure 3: Web application user interface

Clean up

To delete the resources created by the AWS CDK in this tutorial, run the following command:

cdk destroy --all

Conclusion

In this post, we presented an end-to-end workflow for building a semantic search engine for tabular columns.

Get started today on your own data with our code tutorial available on GitHub. If you’d like help accelerating your use of ML in your products and processes, please contact the Amazon Machine Learning Solutions Lab.


About the Authors

Kachi Odoemene is an Applied Scientist at AWS AI. He builds AI/ML solutions to solve business problems for AWS customers.

Taylor McNally is a Deep Learning Architect at Amazon Machine Learning Solutions Lab. He helps customers from various industries build solutions leveraging AI/ML on AWS. He enjoys a good cup of coffee, the outdoors, and time with his family and energetic dog.

Austin Welch is a Data Scientist in the Amazon ML Solutions Lab. He develops custom deep learning models to help AWS public sector customers accelerate their AI and cloud adoption. In his spare time, he enjoys reading, traveling, and jiu-jitsu.

Enhance operational insights for Amazon MSK using Amazon Managed Service for Prometheus and Amazon Managed Grafana

Post Syndicated from Anand Mandilwar original https://aws.amazon.com/blogs/big-data/enhance-operational-insights-for-amazon-msk-using-amazon-managed-service-for-prometheus-and-amazon-managed-grafana/

Amazon Managed Streaming for Apache Kafka (Amazon MSK) is an event streaming platform that you can use to build asynchronous applications by decoupling producers and consumers. Monitoring of different Amazon MSK metrics is critical for efficient operations of production workloads. Amazon MSK gathers Apache Kafka metrics and sends them to Amazon CloudWatch, where you can view them. You can also monitor Amazon MSK with Prometheus, an open-source monitoring application. Many of our customers use such open-source monitoring tools like Prometheus and Grafana, but doing it in self-managed environment comes with its own challenges regarding manageability, availability, and security.

In this post, we show how you can build an AWS Cloud native monitoring platform for Amazon MSK using the fully managed, highly available, scalable, and secure services Amazon Managed service for Prometheus and Amazon Managed Grafana for better operational insights.

Why is Kafka monitoring critical?

As a critical component of the IT infrastructure, it is necessary to track Amazon MSK clusters’ operations and their efficiencies. Amazon MSK metrics helps monitor critical tasks while operating applications. You can not only troubleshoot problems that have already occurred, but also discover anomalous behavior patterns and prevent problems from occurring in the first place.

Some customers currently use various third-party monitoring solutions like lenses.io, AppDynamics, Splunk, and others to monitor Amazon MSK operational metrics. In the context of cloud computing, customers are looking for an AWS Cloud native service that offers equivalent or better capabilities but with the added advantage of being highly scalable, available, secure, and fully managed.

Amazon MSK clusters emit a very large number of metrics via JMX, many of which can be useful for tuning the performance of your cluster, producers, and consumers. However, that large volume brings complexity with monitoring. By default, Amazon MSK clusters come with CloudWatch monitoring of your essential metrics. You can extend your monitoring capabilities by using open-source monitoring with Prometheus. This feature enables you to scrape a Prometheus friendly API to gather all the JMX metrics and work with the data in Prometheus.

This solution provides a simple and easy observability platform for Amazon MSK along with much needed insights into various critical operational metrics that yields the following organizational benefits for your IT operations or application teams:

  • You can quickly drill down to various Amazon MSK components (broker level, topic level, or cluster level) and identify issues that need investigation
  • You can investigate Amazon MSK issues after the event using the historical data in Amazon Managed Service for Prometheus
  • You can shorten or eliminate long calls that waste time questioning business users on Amazon MSK issues

In this post, we set up Amazon Managed Service for Prometheus, Amazon Managed Grafana, and a Prometheus server running as container on Amazon Elastic Compute Cloud (Amazon EC2) to provide a fully managed monitoring solution for Amazon MSK.

The solution provides an easy-to-configure dashboard in Amazon Managed Grafana for various critical operation metrics, as demonstrated in the following video.

Solution overview

Amazon Managed Service for Prometheus reduces the heavy lifting required to get started with monitoring applications across Amazon MSK, Amazon Elastic Kubernetes Service (Amazon EKS), Amazon Elastic Container Service (Amazon ECS), and AWS Fargate, as well as self-managed Kubernetes clusters. The service also seamlessly integrates with Amazon Managed Grafana to simplify data visualization, team management authentication, and authorization.

Grafana empowers you to create dashboards and alerts from multiple sources such as an Amazon Managed Prometheus workspace, CloudWatch, AWS X-Ray, Amazon OpenSearch Service, Amazon Redshift, and Amazon Timestream.

The following diagram demonstrates the solution architecture. This solution deploys a Prometheus server running as a container within Amazon EC2, which constantly scrapes metrics from the MSK brokers and remote write metrics to an Amazon Managed Service for Prometheus workspace. As of this writing, Amazon Managed Service for Prometheus is not able to scrape the metrics directly, therefore a Prometheus server is necessary to do so. We use Amazon Managed Grafana to query and visualize the operational metrics for the Amazon MSK platform.

Solution Architecture

The following are the high-level steps to deploy the solution:

  1. Create an EC2 key pair.
  2. Configure your Amazon MSK cluster and associated resources. We demonstrate how to configure an existing Amazon MSK cluster or create a new one.
    1. Option A:- Modify an existing Amazon MSK cluster
    2. Option B:- Create a new Amazon MSK cluster
  3. Enable AWS IAM Identity Center (successor to AWS Single Sign-On), if not enabled.
  4. Configure Amazon Managed Grafana and Amazon Managed Service for Prometheus.
  5. Configure Prometheus and start the service.
  6. Configure the data sources in Amazon Managed Grafana.
  7. Import the Grafana dashboard.

Prerequisites

git clone https://github.com/aws-samples/amazonmsk-managed-observability
  • You download three CloudFormation template files along with the Prometheus configuration file (prometheus.yml), targets.json file (you need this to update the MSK broker DNS later on), and three JSON files for creating a dashboard within Amazon Managed Grafana.
  • Make sure internet connection is allowed to download docker image of Prometheus from within Prometheus server

1. Create an EC2 key pair

To create your EC2 key pair, complete the following steps:

  1. On the Amazon EC2 console, under Network & Security in the navigation pane, choose Key Pairs.
  2. Choose Create key pair.
  3. For Name, enter DemoMSKKeyPair.
  4. For Key pair type¸ select RSA.
  5. For Private key file format, choose the format in which to save the private key:
    1. To save the private key in a format that can be used with OpenSSH, select .pem.
    2. To save the private key in a format that can be used with PuTTY, select .ppk.

Create EC2 Key Pair - DemoMSKKeyPair

The private key file is automatically downloaded by your browser. The base file name is the name that you specified as the name of your key pair, and the file name extension is determined by the file format that you chose.

  1. Save the private key file in a safe place.

2. Configure your Amazon MSK cluster and associated resources.

Using the following options to configure an existing Amazon MSK cluster or create a new one.

2.a Modify an existing Amazon MSK cluster

If you want to create a new Amazon MSK cluster for this solution, skip to the section – 2.b.Create a new Amazon MSK cluster, otherwise complete the steps in this section to modify an existing cluster.

Validate cluster monitoring settings

We must enable enhanced partition-level monitoring (available at an additional cost) and open monitoring with Prometheus. Note that open monitoring with Prometheus is only available for provisioned mode clusters.

  1. Sign in to the account where the Amazon MSK cluster is that you want to monitor.
  2. Open your Amazon MSK cluster.
  3. On the Properties tab, navigate to Monitoring metrics.
  4. Check the monitoring level for Amazon CloudWatch metrics for this cluster, and choose Edit to edit the cluster.
  5. Select Enhance partition-level monitoring.

Editing monitoring attributes of Amazon MSK Cluster

  1. Check the monitoring label for Open monitoring with Prometheus, and choose Edit to edit the cluster.
  2. Select Enable open monitoring for Prometheus.
  3. Under Prometheus exporters, select JMX Exporter and Note Exporter.

enable Open monitoring with Prometheus

  1. Under Broker log delivery, select Deliver to Amazon CloudWatch Logs.
  2. For Log group, enter your log group for Amazon MSK.
  3. Choose Save changes.

Deploy CloudFormation stack

Now we deploy the CloudFormation stack Prometheus_Cloudformation.yml that we downloaded earlier.

  1. On the AWS CloudFormation console, choose Stacks in the navigation pane.
  2. Choose Create stack.
  3. For Prepare template, select Template is ready.
  4. For Template source, select Upload a template.
  5. Upload the Prometheus_Cloudformation.yml file, then choose Next.

CloudFormation - Create Stack for Prometheus_Cloudformation.yml

  1. For Stack name, enter Prometheus.
  2. VPCID – Provide the VPC ID where your Amazon MSK cluster is deployed (mandatory)
  3. VPCCIdr – Provide the VPC CIDR where your Amazon MSK Cluster is deployed (mandatory)
  4. SubnetID – Provide any one of the subnets ID where your existing Amazon MSK cluster is deployed (mandatory)
  5. MSKClusterName – Provide the name your existing Amazon MSK Cluster
  6. Leave Cloud9InstanceType, KeyName, and LatestAmild as default.
  7. Choose Next.

CloudFormation - Specify stack details for Prometheus Stack

  1. On the Review page, select I acknowledge that AWS CloudFormation might create IAM resources.
  2. Choose Create stack.

You’re redirected to the AWS CloudFormation console, and can see the status as CREATE_IN_PROGRESSS. Wait until the status changes to COMPLETE.

CloudFormation stack creation status for Prometheus Stack

  1. On the stack’s Outputs tab, note the values for the following keys (if you don’t see anything under Outputs tab, click on refresh icon):
    1. PrometheusInstancePrivateIP
    2. PrometheusSecurityGroupId

getting private IP and Security Group ID for Prometheus Stack

Update the Amazon MSK cluster security group

Complete the following steps to update the security group of the existing Amazon MSK cluster to allow communication from the Kafka client and Prometheus server:

  1. On the Amazon MSK console, navigate to your Amazon MSK cluster.
  2. On the Properties tab, under Network settings, open the security group.
  3. Choose Edit inbound rules.
  4. Choose Add rule and create your rule with the following parameters:
    1. Type – Custom TCP
    2. Port range – 11001–11002
    3. Source – The Prometheus server security group ID

Set up your AWS Cloud9 environment

To configure your AWS Cloud9 environment, complete the following steps:

  1. On the AWS Cloud9 console, choose Environments in the navigation pane.
  2. Select Cloud9EC2Bastion and choose Open in Cloud9.

AWS Cloud9 home page

  1. Close the Welcome tab and open a new terminal tab
  2. Create an SSH key file with the contents from the private key file DemoMSKKeyPair using the following command:
    touch /home/ec2-user/environment/EC2KeyMSKDemo

  3. Run the following command to list the newly created key file
    ls -ltr

  4. Open the file, enter the contents of the private key file DemoMSKKeyPair, then save the file.

Updating the key file with the private file content

  1. Change the permissions of the file using the following command:
    chmod 600 /home/ec2-user/environment/EC2KeyMSKDemo

  2. Log in to the Prometheus server using this key file and the private IP noted earlier:
    ssh -i /home/ec2-user/environment/EC2KeyMSKDemo ec2-user@<Private-IP-of-Prometheus-instance>

  3. Once you’re logged in, check if the Docker service is up and running using the following command:
    systemctl status docker

checking docker service status

  1. To exit the server, enter exit and press Enter.

2.b Create a new Amazon MSK cluster

If you don’t have an Amazon MSK cluster running in your environment, or you don’t want to use an existing cluster for this solution, complete the steps in this section.

As part of these steps, your cluster will have the following properties:

Deploy CloudFormation stack

Complete the following steps to deploy the CloudFormation stack MSKResource_Cloudformation.yml:

  1. On the AWS CloudFormation console, choose Stacks in the navigation pane.
  2. Choose Create stack.
  3. For Prepare template, select Template is ready.
  4. For Template source, select Upload a template.
  5. Upload the MSKResource_Cloudformation.yml file, then choose Next.
  6. For Stack name, enter MSKDemo.
  7. Network Configuration – Generic (mandatory)
    1. Stack to be deployed in NEW VPC? (true/false) – if false, you MUST provide VPCCidr and other details under Existing VPC section (Default is true)
    2. VPCCidr – Default is 10.0.0.0/16 for a new VPC. You can have any valid values as per your environment. If deploying in an existing VPC, provide the CIDR for the same
  8. Network Configuration – For New VPC
    1. PrivateSubnetMSKOneCidr (Default is 10.0.1.0/24)
    2. PrivateSubnetMSKTwoCidr (Default is 10.0.2.0/24)
    3. PrivateSubnetMSKThreeCidr (Default is 10.0.3.0/24)
    4. PublicOneCidr (Default is 10.0.0.0/24)
  9. Network Configuration – For Existing VPC (You need at least 4 subnets)
    1. VpcId – Provide the value if you are using any existing VPC to deploy the resources else leave it blank(default)
    2. SubnetID1 – Any one of the existing subnets from the given VPCID
    3. SubnetID2 – Any one of the existing subnets from the given VPCID
    4. SubnetID3 – Any one of the existing subnets from the given VPCID
    5. PublicSubnetID – Any one of the existing subnets from the given VPCID
  10. Leave the remaining parameters as default and choose Next.

Specifying the parameter details for MSKDemo stack

  1. On the Review page, select I acknowledge that AWS CloudFormation might create IAM resources.
  2. Choose Create stack.

You’re redirected to the AWS CloudFormation console, and can see the status as CREATE_IN_PROGRESSS. Wait until the status changes to COMPLETE.

CloudFormation stack creation status

  1. On the stack’s Outputs tab, note the values for the following (if you don’t see anything under Outputs tab, click on refresh icon):
    1. KafkaClientPrivateIP
    2. PrometheusInstancePrivateIP

Set up your AWS Cloud9 environment

Follow the steps as outlined in the previous section to configure your AWS Cloud9 environment.

Retrieve the cluster broker list

To get your MSK cluster broker list, complete the following steps:

  1. On the Amazon MSK console, navigate to your cluster.
  2. In the Cluster summary section, choose View client information.
  3. In the Bootstrap servers section, copy the private endpoint.

You need this value to perform some operations later, such as creating an MSK topic, producing sample messages, and consuming those sample messages.

  1. Choose Done.
  2. On the Properties tab, in the Brokers details section, note the endpoints listed.

These need to be updated in the targets.json file (used for Prometheus configuration in a later step).

3. Enable IAM Identity Center

Before you deploy the CloudFormation stack for Amazon Managed Service for Prometheus and Amazon Managed Grafana, make sure to enable IAM Identity Center.

If you don’t use IAM Identity Center, alternatively, you can set up user authentication via SAML. For more information, refer to Using SAML with your Amazon Managed Grafana workspace.

If IAM Identity Center is currently enabled/configured in another region, you don’t need to enable in your current region.

Complete the following steps to enable IAM Identity Center:

  1. On the IAM Identity Center console, under Enable IAM Identity Center, choose Enable.

Enabling IAM Identity Center

  1. Choose Create AWS organization.

4. Configure Amazon Managed Grafana and Amazon Managed Service for Prometheus

Complete the steps in this section to set up Amazon Managed Service for Prometheus and Amazon Managed Grafana.

Deploy CloudFormation template

Complete the following steps to deploy the CloudFormation stack AMG_AMP_Cloudformation:

  1. On the AWS CloudFormation console, choose Stacks in the navigation pane.
  2. Choose Create stack.
  3. For Prepare template, select Template is ready.
  4. For Template source, select Upload a template.
  5. Upload the AMG_AMP_Cloudformation.yml file, then choose Next.
  6. For Stack name, enter ManagedPrometheusAndGrafanaStack, then choose Next.
  7. On the Review page, select I acknowledge that AWS CloudFormation might create IAM resources.
  8. Choose Create stack.

You’re redirected to the AWS CloudFormation console, and can see the status as CREATE_IN_PROGRESSS. Wait until the status changes to COMPLETE.

  1. On the stack’s Outputs tab, note the values for the following (if you don’t see anything under Outputs tab, click on refresh icon):
    1. GrafanaWorkspaceURL – This is Amazon Managed Grafana URL
    2. PrometheusEndpointWriteURL – This is the Amazon Managed Service for Prometheus write endpoint URL

Outputs information for ManagedPromethusAndGrafana Stack

Create a user for Amazon Managed Grafana

Complete the following steps to create a user for Amazon Managed Grafana:

  1. On the IAM Identity Center console, choose Users in the navigation pane.
  2. Choose Add user.
  3. For Username, enter grafana-admin.
  4. Enter and confirm your email address to receive a confirmation email.

IAM Identity Center - Specifying user information

  1. Skip the optional steps, then choose Add user.

A success message appears at the top of the console.

  1. In the confirmation email, choose Accept invitation and set your user password.

Screenshot showing Invitation link for the new user

  1. On the Amazon Managed Grafana console, choose Workspaces in the navigation pane.
  2. Open the workspace Amazon-Managed-Grafana.
  3. Make a note of the Grafana workspace URL.

You use this URL to log in to view your Grafana dashboards.

  1. On the Authentication tab, choose Assign new user or group.

Amazon Managed Grafana - Workspace information - Assigning user

  1. Select the user you created earlier and choose Assign users and groups.

Amazon Managed Grafana - Assigning user to workspace

  1. On the Action menu, choose what kind of user to make it: admin, editor, or viewer.

Note that your Grafana workspace needs as least one admin user.

  1. Navigate to the Grafana URL you copied earlier in your browser.
  2. Choose Sign in with AWS IAM Identity Center.

Amazon Managed Grafana URL landing page

  1. Log in with your IAM Identity Center credentials.

5. Configure Prometheus and start the service

When you cloned the GitHub repo, you downloaded two configuration files: prometheus.yml and targets.json. In this section, we configure these two files.

  1. Use any IDE (Visual Studio Code or Notepad++) to open prometheus.yml.
  2. In the remote_write section, update the remote write URL and Region.

prometheus.yml file

  1. Use any IDE to open targets.json.
  2. Update the targets with the broker endpoints you obtained earlier.

targets.json file

  1. In your AWS Cloud9 environment, choose File, then Upload Local Files.
  2. Choose Select Files and upload targets.json and prometheus.yml from your local machine.

Upload file dialog page within AWS Cloud9 Environment

  1. In the AWS Cloud9 environment, run the following command using the key file you created earlier:
    ssh -i /home/ec2-user/environment/EC2KeyMSKDemo ec2-user@<Private-IP-of-Prometheus instance> mkdir -p /home/ec2-user/Prometheus

  2. copy targets.json to the Prometheus server:
    scp -i /home/ec2-user/environment/EC2KeyMSKDemo targets.json ec2-user@<Private-IP-of-Prometheus-instance>:/home/ec2-user/prometheus/

  3. copy prometheus.yml to the Prometheus server:
    scp -i /home/ec2-user/environment/EC2KeyMSKDemo prometheus.yml ec2-user@<Private-IP-of-Prometheus-instance>:/home/ec2-user/prometheus/

  4. SSH into the Prometheus server and start the container service for Prometheus
    ssh -i /home/ec2-user/environment/EC2KeyMSKDemo ec2-user@<Private-IP-of-Prometheus instance>

  5. start the prometheus container
    sudo docker run -d -p 9090:9090 --name=prometheus -v /home/ec2-user/prometheus/prometheus.yml:/etc/prometheus/prometheus.yml -v /home/ec2-user/prometheus/targets.json:/etc/prometheus/targets.json prom/prometheus --config.file=/etc/prometheus/prometheus.yml

  6. Check if the Docker service is running:

Start the prometheus container inside Prometheus Server

6. Configure data sources in Amazon Managed Grafana

To configure your data sources, complete the following steps:

  1. Log in to the Amazon Managed Grafana URL.
  2. Choose AWS Data Services in the navigation pane, then choose Data Sources.

Amazon Managed Grafana - Configuring data source

  1. For Service, choose Amazon Managed Service for Prometheus.
  2. For Region, choose your Region.

The correct resource ID is populated automatically.

  1. Select your resource ID and choose Add 1 data source.

Configuring data source for Amazon managed Prometheus

  1. Choose Go to settings.

Configuring data source for Amazon managed Prometheus

  1. For Name, enter Amazon Managed Prometheus and enable Default.

The URL is automatically populated.

  1. Leave everything else as default.

Configuring data source for Amazon managed Prometheus

  1. Choose Save & Test.

If everything is correct, the message Data source is working appears.

Now we configure CloudWatch as a data source.

  1. Choose AWS Data Services, then choose Data source.
  2. For Services, choose CloudWatch.
  3. For Region, choose your correct Region.
  4. Choose Add data source.
  5. Select the CloudWatch data source and choose Go to settings.

Configuring data source with Service as CloudWatch

  1. For Name, enter AmazonMSK-CloudWatch.
  2. Choose Save & Test.

7. Import the Grafana dashboard

You can use the following preconfigured dashboards, which are available to download from the GitHub repo:

  • Kafka Metrics
  • MSK Cluster Overview
  • AWS MSK – Kafka Cluster-CloudWatch

To import your dashboard, complete the following steps:

  1. In Amazon Managed Grafana, choose the plus sign in the navigation pane.
  2. Choose Import.

Importing preconfigured dashboard

  1. Choose Upload JSON file.
  2. Choose the dashboard you downloaded.
  3. Choose Load.

Configuring dashboard by importing the json file

The following screenshot shows your loaded dashboard.

Dashboard showing cluster level metrics

Generate sample data in Amazon MSK (Optional – when you create a new Amazon MSK Cluster)

To generate sample data in Amazon MSK, complete the following steps:

  1. In your AWS Cloud9 environment, log in to the Kafka client.
    ssh -i /home/ec2-user/environment/EC2KeyMSKDemo ec2-user@<Private-IP-of-Kafka Client>

  2. Set the broker endpoint variable
    export MYBROKERS="<Bootstrap Servers Endpoint – captured earlier>"

  3. Run the following command to create a topic called TLSTestTopic60:
    /home/ec2-user/kafka/bin/kafka-topics.sh --command-config /home/ec2-user/kafka/config/client.properties --bootstrap-server $MYBROKERS --create --topic TLSTestTopic60 --partitions 5 --replication-factor 2

  4. Still logged in to the Kafka client, run the following command to start the producer service:
    /home/ec2-user/kafka/bin/kafka-console-producer.sh --producer.config /home/ec2-user/kafka/config/client.properties --broker-list $MYBROKERS --topic TLSTestTopic60

Creating topic and producing messages in Kafka Producer service

  1. Open a new terminal from within your AWS Cloud9 environment and log in to the Kafka client instance
    ssh -i /home/ec2-user/environment/EC2KeyMSKDemo ec2-user@<Private-IP-of-Kafka Client>

  2. Set the broker endpoint variable
    export MYBROKERS="<Bootstrap Servers Endpoint – captured earlier>"

  3. Now you can start the consumer service and see the incoming messages
    /home/ec2-user/kafka/bin/kafka-console-consumer.sh --consumer.config /home/ec2-user/kafka/config/client.properties --bootstrap-server $MYBROKERS --topic TLSTestTopic60 --from-beginning

Starting Kafka consumer service

  1. Press CTRL+C to stop the producer/consumer service.

Kafka metrics dashboards on Amazon Managed Grafana

You can now view your Kafka metrics dashboards on Amazon Managed Grafana:

  • Cluster overall health – Configured using Amazon Managed Service for Prometheus as the data source:
    • Critical metrics

Amazon MSK cluster overview – Configured using Amazon Managed Service for Prometheus as the data source:

  • Critical metrics
  • Cluster throughput (broker-level metrics)

  • Cluster metrics (JVM)

Kafka cluster operation metrics – Configured using CloudWatch as the data source:

  • General overall stats

  • CPU and Memory metrics

Clean up

You will continue to incur costs until you delete the infrastructure that you created for this post. Delete the CloudFormation stack you used to create the respective resources.

If you used an existing cluster, make sure to remove the inbound rules you updated in the security group (otherwise the stack deletion will fail).

  1. On the Amazon MSK console, navigate to your existing cluster.
  2. On the Properties tab, in the Networking settings section, open the security group you applied.
  3. Choose Edit inbound rules.

  1. Choose Delete to remove the rules you added.
  2. Choose Save rules.

Now you can delete your CloudFormation stacks.

  1. On the AWS CloudFormation console, choose Stacks in the navigation pane.
  2. Select ManagedPrometheusAndGrafana and choose Delete.
  3. If you used an existing Amazon MSK cluster, delete the stack Prometheus.
  4. If you created a new Amazon MSK cluster, delete the stack MSKDemo.

Conclusion

This post showed how you can deploy a fully managed, highly available, scalable, and secure monitoring system for Amazon MSK using Amazon Managed Service for Prometheus and Amazon Managed Grafana, and use Grafana dashboards to gain deep insights into various operational metrics. Although this post only discussed using Amazon Managed Service for Prometheus and CloudWatch as the data sources in Amazon Managed Grafana, you can enable various other data sources, such as AWS IoT SiteWise, AWS X-Ray, Redshift, and Amazon Athena, and build a dashboard on top of those metrics. You can use these managed services for monitoring any number of Amazon MSK platforms. Metrics are available to query in Amazon Managed Grafana or Amazon Managed Service for Prometheus in near-real time.

You can use this post as prescriptive guidance and deploy an observability solution for a new or an existing Amazon MSK cluster, identify the metrics that are important for your applications and then create a dashboard using Amazon Managed Grafana and Prometheus.


About the Authors

Anand Mandilwar is an Enterprise Solutions Architect at AWS. He works with enterprise customers helping customers innovate and transform their business in AWS. He is passionate about automation around Cloud operation , Infrastructure provisioning and Cloud Optimization. He also likes python programming. In his spare time, he enjoys honing his photography skill especially in Portrait and landscape area.

Ajit Puthiyavettle is a Solution Architect working with enterprise clients, architecting solutions to achieve business outcomes. He is passionate about solving customer challenges with innovative solutions. His experience is with leading DevOps and security teams for enterprise and SaaS (Software as a Service) companies. Recently he is focussed on helping customers with Security, ML and HCLS workload.

Content Repository for Unstructured Data with Multilingual Semantic Search: Part 1

Post Syndicated from Patrik Nagel original https://aws.amazon.com/blogs/architecture/content-repository-for-unstructured-data-with-multilingual-semantic-search-part-1/

Unstructured data can make up to 80 percent of data in the day-to-day business of financial organizations. For example, these organizations typically store and read PDFs and images for claim processing, underwriting, and know your customer (KYC). Organizations need to make this ingested data accessible and searchable across different entities while logically separating data access according to role requirements.

In this two-part series, we use AWS services to build an end-to-end content repository for storing and processing unstructured data with the following features:

  • Dynamic access control-based logic over unstructured data
  • Multilingual semantic search capabilities

In part 1, we build the architectural foundation for the content repository, including the resource access control logic and a web UI to upload and list documents.

Solution overview

The content repository includes four building blocks:

Frontend and interaction: For this function, we use AWS Amplify, which is a set of purpose-built tools and features to help frontend web and mobile developers quickly build full-stack applications on AWS. The React application uses the AWS Amplify authentication feature to quickly set up a complete authentication flow integrated into Amazon Cognito. Amplify also hosts the frontend application.

Authentication and authorization: Implementing dynamic resource access control with a combination of roles and attributes is fundamental to your content repository security. Amazon Cognito provides a managed, scalable user directory, user sign-up and sign-in flows, and federation capabilities through third-party identity providers. We use Amazon Cognito user pools as the source of user identity for the content repository. You can work with user pool groups to represent different types of user collection, and you can manage their permissions using a group-associated AWS Identity and Access Management (IAM) role.

Users authenticate against the Amazon Cognito user pool. The web app will exchange the user pool tokens for AWS credentials through an Amazon Cognito identity pool in the content repository. You can complement the IAM role-based authorization model by mapping your relevant attributes to principal tags that will be evaluated as part of IAM permission policies. This allows a dynamic and flexible authorization strategy. For use cases that need federation with third-party identity providers, you can base your user collection on existing user group attributes, such as Active Directory group membership.

Backend and business logic: Authenticated users are redirected to the Amazon API Gateway. API Gateway provides managed publishing for application programming interfaces (APIs) that act as the repository’s “front door.” API Gateway also interacts with the repository’s backend through RESTful APIs. This makes the business logic of the content repository extensible for future use cases, such as transcription and translation. We use AWS Lambda as a serverless, event-driven compute service to run specific business logic code, such as uploading a document to the content repository.

Content storage: Amazon Simple Storage Service (Amazon S3) provides virtually unlimited scalability and high durability. With Amazon S3, you can cost-effectively store unstructured documents in their native formats and make it accessible in a secure and scalable way. Enriching the uploaded documents with tags simplifies data governance with fine-grained access control.

Technical architecture

The technical architecture of the content repository with these four components can be found in Figure 1.

Technical architecture of the content repository

Figure 1. Technical architecture of the content repository

Let’s explore the architecture step by step.

  1. The frontend uses the Amplify JS library to add the authentication UI component to your React app, allowing authenticated users to sign in.
  2. Once the user provides their sign-in credentials, they are redirected to Amazon Cognito user pools to be authenticated.
  3. Once the authentication is successful, Amazon Cognito invokes a pre-token generation Lambda function. This function customizes the identity (ID) token with a new claim called department. This new claim is the Amazon Cognito group name from the cognito:preferred_role claim.
  4. Amazon Cognito returns the identity, access, and refresh token in JSON format to the frontend.
  5. The Amplify client library stores the tokens and handles refreshes using the refresh token while the React frontend application calls the API Gateway with the ID token. Note: Usually, you would use the access token to grant access to authorized resources. For this architecture, we use the ID token because we have enriched it with the custom claim during step 3.
  6. API Gateway uses its native integration with Amazon Cognito and validates the ID token’s signature and expiration using Amazon Cognito user pool authorizer. For more complex authorization scenarios, you can use API Gateway Lambda authorizer with the AWS JSON Web Token (JWT) Verify library for verifying JWTs signed by Amazon Cognito.
  7. After successful validation, API Gateway passes the ID token to the backend Lambda function, which can verify and authorize upon it for access control.
  8. Upon document upload action, the backend Lambda function calls the Amazon Cognito identity pool to exchange the ID token for the temporary AWS credentials associated with the cognito:preferred_role claim.
  9. The document upload Lambda function returns a pre-signed URL with the custom department claim in the Amazon S3 path prefix as well as the object tag. The Amazon S3 pre-signed URL is used for the document upload from the frontend application directly to Amazon S3.
  10. Upon document list action, similar to step 8, the backend Lambda function exchanges the ID token for the temporary AWS credentials. The Lambda function returns only the documents based on the user’s preferred group and associated custom department claim.

Prerequisites

You must have the following prerequisites for this solution:

Walkthrough

Setup

The following steps will deploy two AWS CDK stacks into your AWS account:

  • content-repo-stack (blog-content-repo-stack.ts) creates the environment detailed in Figure 1.
  • demo-data-stack (userpool-demo-data-stack.ts) deploys sample users, groups, and role mappings.

To continue setup, use the following commands:

  1. Clone the project git repository:
    git clone https://github.com/aws-samples/content-repository-with-dynamic-access-control content-repository
  2. Install the necessary dependencies:
    cd content-repository/backend-cdk
    npm install
    
  3. Configure environment variables:
    export CDK_DEFAULT_ACCOUNT=$(aws sts get-caller-identity --query 'Account' --output text)
    export CDK_DEFAULT_REGION=$(aws configure get region)
    
  4. Bootstrap your account for AWS CDK usage:
    cdk bootstrap aws://$CDK_DEFAULT_ACCOUNT/$CDK_DEFAULT_REGION
  5. Deploy the code to your AWS account:
    cdk deploy --all

Using the repository

Once you deploy the CDK stacks in your AWS account, follow these steps:

1. Access the frontend application:

a. Copy the amplifyHostedAppUrl value shown in the AWS CDK output from the content-repo-stack.

b. Use the URL with your web browser to access the frontend application.

c. A temporary page displays until the automated build and deployment of the React application completes after 4-5 minutes.

2. Application sign-in and role-based access control (RBAC):

a. The React webpage prompts you to sign in and then change the temporary password.

b. The content repository provides two demo users with credentials as part of the demo-data-stack in the AWS CDK output. In this walkthrough, we use the sales-user user, which belongs to the sales department group to validate RBAC.

3. Upload a document to the content repository:

a. Authenticate as sales-user.

b. Select upload to upload your first document to the content repository.

c. The repository provides sample documents in the assets sub-folder.

4. List your uploaded document:

a. Select list to show the uploaded sales content.

b. To verify the dynamic access control, repeat steps 2 and 3 for the marketing-user user, which belongs to the marketing department group.

c. Sign-in to the AWS Management Console and navigate to the Amazon S3 bucket with the prefix content-repo-stack-s3sourcebucket to confirm that all the uploaded content exists.

Implementation notes

Frontend deployment and cross-origin access

The content-repo-stack contains an AwsCustomResource construct. This construct uses the Amplify API to start the release job of the Amplify hosted frontend application. The preBuild step of the Amplify application build specification dynamically configures its backend for the Amazon Cognito-based authentication. The required Amazon Cognito configuration parameters are retrieved from the AWS Systems Manager Parameter Store during build time. Similarly, the Amplify application postBuild step updates the Amazon S3 cross-origin resource sharing (CORS) rule for the Amazon S3 bucket to only allow cross-origin access from the Amplify-hosted URL of the frontend application.

Application sign-in and access control

The Amazon Cognito identity pool configuration is set to Choose role from token for authenticated users, as in Figure 2. This setup permits authenticated users to pass the roles in the ID token that the Amazon Cognito user pool assigned. Backend Lambda functions use the roles that appear in the cognito:roles and cognito:preferred_role claims in the ID token for RBAC.

Amazon Cognito identity pool configuration – using tokens to assign roles to authenticated users

Figure 2. Amazon Cognito identity pool configuration – using tokens to assign roles to authenticated users

In the attributes for access control section, we configured a custom mapping from the augmented department token claim to a tag key, as in Figure 3. The backend logic uses the tag key to match the PrincipalTag condition in IAM policies to control access to AWS resources.

Amazon Cognito identity pool configuration – custom mapping from claim names to tag keys

Figure 3. Amazon Cognito identity pool configuration – custom mapping from claim names to tag keys

Document upload

The presigned_url.py Lambda function generates a pre-signed Amazon S3 URL using the department token claim as the key. This function automatically organizes the uploaded document into a logical structure in the Amazon S3 source bucket. Accordingly, the cognito:preferred_role used for the Amazon S3 client credentials in the Lambda function has a permission policy using the PrincipalTag department to dynamically limit access to the Amazon S3 key, as in Figure 4.

Permission policy using PrincipalTag to upload documents to Amazon S3

Figure 4. Permission policy using PrincipalTag to upload documents to Amazon S3

Document listing

The list functionality only shows the uploaded content belonging to the preferred group of authenticated Amazon Cognito user pool user. To only list the files that a specific user (for example, sales-user) has access to, use the PrincipalTag s3:prefix condition, as in Figure 5.

Permission policy using s3:prefix condition with session tags to list documents

Figure 5. Permission policy using s3:prefix condition with session tags to list documents

Cleanup

In the backend-cdk subdirectory, delete the deployed resources:

cdk destroy --all

Conclusion

In this blog, we demonstrated how to build a content repository with an easy-to-use web application for unstructured data that ingests documents while maintaining dynamic access control for users within departments. These steps provide a foundation to build your own content repository to store and process documents. As next steps, based on your organization’s security requirements, you can implement more complex access control use cases by balancing IAM role and principal tags. For example, you can use Amazon Cognito user pool custom attributes for additional dimensions such as document “clearance” with optional modification in the pre-token generation Lambda.

In the next part of this blog series, we will enrich the content repository with multi-lingual semantic search features while maintaining the access control fundamentals we’ve already implemented. For additional information on how you can build a solution to search for information across multiple scanned documents, PDFs, and images with compliance capabilities, please refer our Document Understanding Solution from AWS Solutions Library.

Proactive Insights with Amazon DevOps Guru for RDS

Post Syndicated from Kishore Dhamodaran original https://aws.amazon.com/blogs/devops/proactive-insights-with-amazon-devops-guru-for-rds/

Today, we are pleased to announce a new Amazon DevOps Guru for RDS capability: Proactive Insights. DevOps Guru for RDS is a fully-managed service powered by machine learning (ML), that uses the data collected by RDS Performance Insights to detect and alert customers of anomalous behaviors within Amazon Aurora databases. Since its release, DevOps Guru for RDS has empowered customers with information to quickly react to performance problems and to take corrective actions. Now, Proactive Insights adds recommendations related to operational issues that may prevent potential issues in the future.

Proactive Insights requires no additional set up for customers already using DevOps Guru for RDS, for both Amazon Aurora MySQL-Compatible Edition and Amazon Aurora PostgreSQL-Compatible Edition.

The following are example use cases of operational issues available for Proactive Insights today, with more insights coming over time:

  • Long InnoDB History for Aurora MySQL-Compatible engines – Triggered when the InnoDB history list length becomes very large.
  • Temporary tables created on disk for Aurora MySQL-Compatible engines – Triggered when the ratio of temporary tables created versus all temporary tables breaches a threshold.
  • Idle In Transaction for Aurora PostgreSQL-Compatible engines – Triggered when sessions connected to the database are not performing active work, but can keep database resources blocked.

To get started, navigate to the Amazon DevOps Guru Dashboard where you can see a summary of your system’s overall health, including ongoing proactive insights. In the following screen capture, the number three indicates that there are three ongoing proactive insights. Click on that number to see the listing of the corresponding Proactive Insights, which may include RDS or other Proactive Insights supported by Amazon DevOps Guru.

Amazon DevOps Guru Dashboard where you can see a summary of your system’s overall health, including ongoing proactive insights

Figure 1. Amazon DevOps Guru Dashboard where you can see a summary of your system’s overall health, including ongoing proactive insights.

Ongoing problems (including reactive and proactive insights) are also highlighted against your database instance on the Database list page in the Amazon RDS console.

Proactive and Reactive Insights are highlighted against your database instance on the Database list page in the Amazon RDS console

Figure 2. Proactive and Reactive Insights are highlighted against your database instance on the Database list page in the Amazon RDS console.

In the following sections, we will dive deep on these use cases of DevOps Guru for RDS Proactive Insights.

Long InnoDB History for Aurora MySQL-Compatible engines

The InnoDB history list is a global list of the undo logs for committed transactions. MySQL uses the history list to purge records and log pages when transactions no longer require the history.  If the InnoDB history list length grows too large, indicating a large number of old row versions, queries and even the database shutdown process can become slower.

DevOps Guru for RDS now detects when the history list length exceeds 1 million records and alerts users to close (either by commit or by rollback) any unnecessary long-running transactions before triggering database changes that involve a shutdown (this includes reboots and database version upgrades).

From the DevOps Guru console, navigate to Insights, choose Proactive, then choose “RDS InnoDB History List Length Anomalous” Proactive Insight with an ongoing status. You will notice that Proactive Insights provides an “Insight overview”, “Metrics” and “Recommendations”.

Insight overview provides you basic information on this insight. In our case, the history list for row changes increased significantly, which affects query and shutdown performance.

Long InnoDB History for Aurora MySQL-Compatible engines Insight overview

Figure 3. Long InnoDB History for Aurora MySQL-Compatible engines Insight overview.

The Metrics panel gives you a graphical representation of the history list length and the timeline, allowing you to correlate it with any anomalous application activity that may have occurred during this window.

Long InnoDB History for Aurora MySQL-Compatible engines Metrics panel

Figure 4. Long InnoDB History for Aurora MySQL-Compatible engines Metrics panel.

The Recommendations section suggests actions that you can take to mitigate this issue before it leads to a bigger problem. You will also notice the rationale behind the recommendation under the “Why is DevOps Guru recommending this?” column.

The Recommendations section suggests actions that you can take to mitigate this issue before it leads to a bigger problem

Figure 5. The Recommendations section suggests actions that you can take to mitigate this issue before it leads to a bigger problem.

Temporary tables created on disk for Aurora MySQL-Compatible engines

Sometimes it is necessary for the MySQL database to create an internal temporary table while processing a query. An internal temporary table can be held in memory and processed by the TempTable or MEMORY storage engine, or stored on disk by the InnoDB storage engine. An increase of temporary tables created on disk instead of in memory can impact the database performance.

DevOps Guru for RDS now monitors the rate at which the database creates temporary tables and the percentage of those temporary tables that use disk. When these values cross recommended levels over a given period of time, DevOps Guru for RDS creates an insight exposing this situation before it becomes critical.

From the DevOps Guru console, navigate to Insights, choose Proactive, then choose “RDS Temporary Tables On Disk Anomalous” Proactive Insight with an ongoing status. You will notice this Proactive Insight provides an “Insight overview”, “Metrics” and “Recommendations”.

Insight overview provides you basic information on this insight. In our case, more than 58% of the total temporary tables created per second were using disk, with a sustained rate of two temporary tables on disk created every second, which indicates that query performance is degrading.

Temporary tables created on disk insight overview

Figure 6. Temporary tables created on disk insight overview.

The Metrics panel shows you a graphical representation of the information specific for this insight. You will be presented with the evolution of the amount of temporary tables created on disk per second, the percentage of temporary tables on disk (out of the total number of database-created temporary tables), and of the overall rate at which the temporary tables are created (per second).

Temporary tables created on disk evolution of the amount of temporary tables created on disk per second

Figure 7. Temporary tables created on disk – evolution of the amount of temporary tables created on disk per second.

Temporary tables created on disk the percentage of temporary tables on disk (out of the total number of database-created temporary tables)

Figure 8. Temporary tables created on disk – the percentage of temporary tables on disk (out of the total number of database-created temporary tables).

Temporary tables created on disk overall rate at which the temporary tables are created (per second)

Figure 9. Temporary tables created on disk – overall rate at which the temporary tables are created (per second).

The Recommendations section suggests actions to avoid this situation when possible, such as not using BLOB and TEXT data types, tuning tmp_table_size and max_heap_table_size database parameters, data set reduction, columns indexing and more.

Temporary tables created on disk actions to avoid this situation when possible, such as not using BLOB and TEXT data types, tuning tmp_table_size and max_heap_table_size database parameters, data set reduction, columns indexing and more

Figure 10. Temporary tables created on disk – actions to avoid this situation when possible, such as not using BLOB and TEXT data types, tuning tmp_table_size and max_heap_table_size database parameters, data set reduction, columns indexing and more.

Additional explanations on this use case can be found by clicking on the “View troubleshooting doc” link.

Idle In Transaction for Aurora PostgreSQL-Compatible engines

A connection that has been idle in transaction  for too long can impact performance by holding locks, blocking other queries, or by preventing VACUUM (including autovacuum) from cleaning up dead rows.
PostgreSQL database requires periodic maintenance, which is known as vacuuming. Autovacuum in PostgreSQL automates the execution of VACUUM and ANALYZE commands. This process gathers the table statistics and deletes the dead rows. When vacuuming does not occur, this negatively impacts the database performance. It leads to an increase in table and index bloat (the disk space that was used by a table or index and is available for reuse by the database but has not been reclaimed), leads to stale statistics and can even end in transaction wraparound (when the number of unique transaction ids reaches its maximum of about two billion).

DevOps Guru for RDS monitors the time spent by sessions in an Aurora PostgreSQL database in idle in transaction state and raises initially a warning notification, followed by an alarm notification if the idle in transaction state continues (the current thresholds are 1800 seconds for the warning and 3600 seconds for the alarm).

From the DevOps Guru console, navigate to Insights, choose Proactive, then choose “RDS Idle In Transaction Max Time Anomalous” Proactive Insight with an ongoing status. You will notice this Proactive Insights provides an “Insight overview”, “Metrics” and “Recommendations”.

In our case, a connection has been in “idle in transaction” state for more than 1800 seconds, which could impact the database performance.

A connection has been in “idle in transaction” state for more than 1800 seconds, which could impact the database performance

Figure 11. A connection has been in “idle in transaction” state for more than 1800 seconds, which could impact the database performance.

The Metrics panel shows you a graphical representation of when the long-running “idle in transaction” connections started.

The Metrics panel shows you a graphical representation of when the long-running “idle in transaction” connections started

Figure 12. The Metrics panel shows you a graphical representation of when the long-running “idle in transaction” connections started.

As with the other insights, recommended actions are listed and a troubleshooting doc is linked for even more details on this use case.

Recommended actions are listed and a troubleshooting doc is linked for even more details on this use case

Figure 13. Recommended actions are listed and a troubleshooting doc is linked for even more details on this use case.

Conclusion

With Proactive Insights, DevOpsGuru for RDS enhances its abilities to help you monitor your databases by notifying you about potential operational issues, before they become bigger problems down the road. To get started, you need to ensure that you have enabled Performance Insights on the database instance(s) you want monitored, as well as ensure and confirm that DevOps Guru is enabled to monitor those instances (for example by enabling it at account level, by monitoring specific CloudFormation stacks or by using AWS tags for specific Aurora resources). Proactive Insights is available in all regions where DevOps Guru for RDS is supported. To learn more about Proactive Insights, join us for a free hands-on Immersion Day (available in three time zones) on March 15th or April 12th.

About the authors:

Kishore Dhamodaran

Kishore Dhamodaran is a Senior Solutions Architect at AWS.

Raluca Constantin

Raluca Constantin is a Senior Database Engineer with the Relational Database Services (RDS) team at Amazon Web Services. She has 16 years of experience in the databases world. She enjoys travels, hikes, arts and is a proud mother of a 12y old daughter and a 7y old son.

Jonathan Vogel

Jonathan is a Developer Advocate at AWS. He was a DevOps Specialist Solutions Architect at AWS for two years prior to taking on the Developer Advocate role. Prior to AWS, he practiced professional software development for over a decade. Jonathan enjoys music, birding and climbing rocks.

Considerations for the security operations center in the cloud: deployment using AWS security services

Post Syndicated from Stuart Gregg original https://aws.amazon.com/blogs/security/considerations-for-the-security-operations-center-in-the-cloud-deployment-using-aws-security-services/

Welcome back. If you’re joining this series for the first time, we recommend that you read the first blog post in this series, Considerations for security operations in the cloud, for some context on what we will discuss and deploy in this blog post. In the earlier post, we talked through the different operating models (centralized, decentralized, or hybrid) that you can deploy for a Security Operations Center (SOC) function when you operate in the cloud. We covered the advantages of each model and some of the potential drawbacks you might see when you start to scale up operations within the cloud.

This post will focus on the Amazon Web Services (AWS) native security service, AWS Security Hub, that you can use to deploy in different SOC operating models. AWS Security Hub is a cloud security posture management service that SOC teams can use to perform security best practice checks and aggregate alerts. AWS Security Hub accepts findings from multiple sources, whether native to AWS, from the pre-built integrations, or from your own sources converted into the AWS Security Finding Format (ASFF). The data collected in Security Hub facilitates response and remediation actions.

Although the models we describe here use services that are native to AWS, the reference architectures that correspond to each operating model can be applied to a variety of deployments, including multi-cloud and traditional on-premises deployments. The majority of this post will focus on the decentralized and hybrid models—the centralized model is well documented and has reference architectures already available for you today.

Each organization is different, and no one operating model will fit everyone. You should choose the model that works best for your organizational landscape, with an understanding that the landscape will change and evolve over time. Using feedback loops and being open to change is important to help you meet the continued needs of your business. Additional factors to consider include, but are not limited to: staff skills, compliance requirements, previous operating model, and budget.

The centralized model

The centralized operating model for the SOC is well documented and frequently discussed, both at AWS and in the security community. According to AWS best practices, typically you designate a central security tooling account that is dedicated to operating security services, monitoring AWS accounts, and automating security alerting and response. The security tooling account serves as the administrator account for security services that are managed in an administrator/member structure across your AWS accounts. The key objectives for establishing a security tooling account are the following:

  • Provide a dedicated enclave with controlled access for managing security guardrails, monitoring, and response.
  • Maintain the appropriate centralized security infrastructure to monitor security operations data and maintain traceability across the security lifecycle.

Figure 1 demonstrates the variety of AWS security services that you can deploy in the central security account. For example, Security Hub within the security tooling account can act as the administrator to enable Security Hub in the member accounts, as well as view findings, view insights, and set security standards across member accounts, which can help simplify security posture management across your existing and future accounts.

Figure 1: Reference architecture for the security tooling account in a centralized model

Figure 1: Reference architecture for the security tooling account in a centralized model

As mentioned earlier, you can enable Security Hub to administer and enable member accounts. This is achieved by using AWS Organizations and the delegated administrator functionality. In addition, you can use Security Hub cross-Region aggregation within the delegated administrator account to aggregate findings, finding updates, insights, control compliance statuses, and security scores from multiple Regions to a single aggregation Region. You can then manage this data from the aggregation Region. Figure 2 shows the reference architecture for this functionality.

Figure 2: Reference architecture for Security Hub in the delegated administrator model

Figure 2: Reference architecture for Security Hub in the delegated administrator model

The AWS Security Reference Architecture (AWS SRA) is a great starting point for establishing the centralized security operations model. The AWS SRA is a holistic set of guidelines for deploying the full complement of AWS security services in a multi-account environment. You can use it to help design, implement, and manage AWS security services so that they align with AWS best practices. The AWS SRA’s Security Hub Organization solution provides deployable templates and examples that automate the process of enabling Security Hub by delegating administration to an account and configuring Security Hub for the existing and future AWS Organizations accounts.

The decentralized and hybrid models

As mentioned in Considerations for security operations in the cloud, the decentralized and hybrid SOC models provide many benefits for organizations. The flexibility of these operating models allows organizational units (OUs) to control how they deal with security-related incidents while still having organization-wide visibility into security posture. This flexibility is important as organizations start to scale up activities within the cloud.

The reference architecture in Figure 3 shows how the benefits we discussed in our earlier blog post can be architected in the decentralized and hybrid operating models in the AWS Cloud.

Figure 3: Reference architecture for the decentralized and hybrid operating models in AWS

Figure 3: Reference architecture for the decentralized and hybrid operating models in AWS

The key features of this architecture are as follows:

  1. The organization root account is separate, according to AWS Organizations best practices. By using service control policies (SCPs), the root account can still achieve a level of governance across the business.
  2. Dedicated accounts have been created for each OU for the Security Hub administration. The model we will use for this deployment is the invite model. In this reference architecture and as an example, we’re using Amazon GuardDuty to flow findings into Security Hub. When you use this model, each OU can manage findings for that OU. This gives you flexibility to work from the Security Hub admin with full visibility of the OU and accounts associated with that OU, or to work in each member account and view findings for that account only.
  3. (Optional, for use with the hybrid model) Each OU’s Security Hub member accounts first send events to their Security Hub admin account. The Security Hub admin account will then send events for that OU to the local Amazon EventBridge bus. You can then set up rules to forward events to a central EventBridge bus in a dedicated AWS account. In the architecture in Figure 3, this account is named SecAnalytics. This step will follow a similar flow as the one described in this AWS Cloud Operations & Migrations blog post.
  4. (Optional, for use with the hybrid model) After the OUs have sent data to the central bus, you can use a capability similar to the one in this AWS Architecture Blog post to start organizing the findings and gain organization-wide visibility. The solution in the earlier post used Amazon QuickSight to visualize the data, but you can use another tool or pre-existing data pipeline.

Items 3 and 4 labeled with (Optional) are capabilities that enable the hybrid model; these are not required if you only want to enable the decentralized model.

Considerations for all deployments

Keep the following considerations in mind for all deployments:

  • Steady state operations should be considered for whichever model you deploy in. For the centralized model, you can use functionality within AWS Organizations to automatically enable Security Hub for accounts within the organization. In the decentralized and hybrid models, you will need to build out this capability or use a similar capability as described in this repo.
  • Alert fatigue happens when humans work on the same repetitive tasks’ day in and day out. To help reduce this, within the reference architecture and solution overview, we’ve added the capability described in this Security Blog post to automatically suppress findings based on criteria set by you. For the centralized model, you can add this capability in the delegated admin account for Security Hub. For the decentralized and hybrid models, we recommend that you put the auto-suppression capability in the Security Hub admin account, and then centralize the rules for suppression for that OU at the Security Hub admin level. This will reduce the overhead for deploying suppression rules multiple times and give a single location where rules are placed for that OU.
  • Context is key. Within the reference architecture and solution overview for decentralized and hybrid deployments, we’ve added the capability described in this Security Blog post. This capability will add additional context, such as the account name, the OU associated with the account, security contact information, and account tags. This information is pulled from AWS Organizations to enrich Security Hub findings. This additional context can also be used in the centralized model.

Deploy the decentralized and hybrid models

In this section, we’ll walk you through the deployment that reflects the reference architecture for the decentralized and hybrid models. Figure 4 shows the solution architecture, including the solution that needs to be deployed in the Security Hub admin account and in the aggregation Region for each business unit within the organization. The solution provides the capability to suppress Security Hub findings, enrich the findings, and propagate findings to central security accounts.

Figure 4: Reference architecture for the decentralized and hybrid deployment

Figure 4: Reference architecture for the decentralized and hybrid deployment

The solution architecture consists of the following:

  • An EventBridge rule to invoke a Lambda function (Suppression Lambda) as the target to suppress any findings based on specific generator IDs within specific member accounts.

    Note: The Security Hub Generator IDs and AWS Account IDs in the EventBridge rule are left as placeholders so that you can fill based on your needs.

  • An EventBridge rule to invoke a Lambda function (Enrichment Lambda) as the target to enrich the findings with AWS account and OU related metadata, along with alternate contact information to better prioritize the findings. The API calls to AWS Organizations and AWS account management services are optimized by caching the metadata in an Amazon DynamoDB table with a time-to-live (TTL) value of 24 hours.
  • An EventBridge rule to post the enriched findings that were not suppressed to a custom EventBridge event bus in the organization-level Security Tooling/SecAnalytics account.

Prerequisites

The following are the prerequisites for this deployment:

  • AWS Organizations is utilized across the business. In this scenario, AWS Organizations will be used to group AWS accounts into OUs, as well as to provide enrichment data for Security Hub findings.
  • Alternative contacts for AWS accounts have been filled out with the most up-to-date information. This is a best practice recommendation. This information will be used for enrichment of the Security Hub findings.
  • Your organization already has a pipeline in place for indexing Security Hub findings and visualizing them.
  • Security Hub is set up in the invite model. OU-level Security Hub accounts have been invited and accepted to be managed by the OU-level Security Hub admin account.
  • The grouping of findings across multiple OU-level Security Hub admin accounts uses Amazon EventBridge to forward events to a centralized bus. You should have the event bus set up ready for this deployment.

Deploy the solution

This solution deployment consists of two parts:

  1. Create an IAM role in your Organizations management account that allows BU-level Security Hub admin to access account metadata, as described in the Create the IAM role procedure that follows.
  2. Deploy the Enrichment Lambda function, the Suppression Lambda function, and the associated EventBridge event rules within the BU-level Security Hub administrator account.

Create the IAM role

Follow the instructions in Creating a role to delegate permissions to an IAM user to create an IAM role by using the IAM console, AWS Command Line Interface (AWS CLI), or AWS API. Create the role in the AWS Organizations management account with the role name as account-contact-readonly, based on the following trust and permission policy templates. You will need the account ID of your BU-level Security Hub administrator account.

The IAM trust policy allows the Security Hub administrator account to assume the role in your Organizations management account.

Note: The following trust policy shows only one BU Security admin account. You will need to add all BU Security admin accounts to the trust policy.

IAM role trust policy

{
   "Version": "2012-10-17",
   "Statement": [
     {
       "Effect": "Allow",
       "Principal": {
         "AWS": "arn:aws:iam::<BU SecHubAdmin Account ID>:root"
       },
       "Action": "sts:AssumeRole",
       "Condition": {}
     }
   ]
 }

Note: Replace <BU SecHubAdmin Account ID> with the account ID of your decentralized BU-level Security Hub administrator account. After the solution is deployed, you should update the principal in the preceding trust policy to use the new IAM role created for the solution.

IAM permission policy

{
     "Version": "2012-10-17",
     "Statement": [
         {
            "Action": "Account:GetAlternateContact",
            "Resource": [
                "arn:aws:account::<Org Management Account ID>:account/o-*/*"
            ],
            "Effect": "Allow"
        },
        {
            "Action": [
                "organizations:DescribeAccount",
                "organizations:ListTagsForResource",
                "organizations:DescribeOrganizationalUnit",
                "organizations:ListParents"
            ],
            "Resource": [
                "arn:aws:organizations::<Org Management Account ID>:account/o-*/*",
                "arn:aws:organizations::<Org Management Account ID>:ou/o-*/ou-*"
            ],
            "Effect": "Allow"
        }
     ]
 }

The IAM permission policy allows the Security Hub administrator account to look up the alternate contact information for the member accounts.

Make a note of the role Amazon Resource Name (ARN) for the IAM role, which will be similar to this format:
arn:aws:iam::<Org Management Account ID>:role/account-contact-readonly.

You will need this ARN when you deploy the solution in the next procedure.

Use AWS CloudFormation to create the IAM role

Alternatively, you can use the CloudFormation template we provide in our GitHub repository to create the role in the management account. The IAM role ARN is available in the Outputs section of the created CloudFormation stack.

Deploy the solution to your BU-level Security Hub administrator account

After you have the IAM role created, you can deploy the solution either from the AWS Management Console, or from our GitHub repository by using the AWS SAM CLI.

Note: If you’ve designated an aggregation Region within the BU-level Security Hub administrator account, you can deploy this solution only in the aggregation Region. Otherwise, you need to deploy this solution separately in each Region of the BU-level Security Hub administrator account where Security Hub is enabled.

To deploy the solution by using the AWS Management Console

  1. In your Security Hub administrator account, launch the template by choosing the following Launch Stack button, which creates the stack the in us-east-1 Region.

    Launch Stack stack

    Note: If your Security Hub aggregation Region is different than us-east-1 or you want to deploy the solution in a different AWS Region, you can deploy the solution from the GitHub repository described in the next section.

  2. On the Quick create stack page, for Stack name, enter a unique stack name for this account; for example, aws-security-hub-decentralized-deployment-stack. 
     
    Figure 5: Quick create CloudFormation stack for the solution

    Figure 5: Quick create CloudFormation stack for the solution

  3. For SecurityToolingAccountEventBus, provide the EventBus ARN in the security tooling account to post the Security Hub findings from the BU-level Security Hub administrator account.
  4. For OrgManagementAccountContactRole, enter the role ARN of the role you created previously in the Create IAM role procedure.
  5. Choose Create stack.
  6. After the stack is created, go to the Resources tab and take note of the name of the IAM role that was created.
  7. Update the principal element of the IAM role trust policy that you previously created in the Organizations management account in the Create the IAM role procedure, replacing the existing value with the role name you noted down.

To deploy the solution from our GitHub repository and AWS SAM CLI

  1. Install the AWS SAM CLI.
  2. Download or clone the GitHub repository by using the following commands.

    git clone https://github.com/aws-samples/aws-securityhub-decentralized-operations-solution.git
    cd aws-securityhub-decentralized-operations-solution

  3. Update the content of the profile.txt file with the profile name you want to use for the deployment.
  4. To create a new bucket for deployment artifacts, run create-bucket.sh by specifying the Region as argument.

    $ ./create-bucket.sh us-east-1

  5. Deploy the solution to the account by running the deploy.sh script by specifying the Region as argument.

    $ ./deploy.sh us-east-1

  6. After the stack is created, go to the Resources tab and take note of the name of the IAM role that was created.
  7. Update the principal element of the IAM role trust policy that you previously created in the Organizations management account in the Create the IAM role procedure, replacing it with the role name you noted down.

    "AWS": "arn:aws:iam::<BU SH Delegated Account ID>: role/<Role Name>"

Note: The EventBridge rule to invoke the findings suppression Lambda function uses placeholders for the generator IDs and AWS account IDs. You need to update the EventBridge rule to meet your specific organizational requirements.

Further enhancements and conclusion

Beyond what is described in the decentralized and hybrid models, you can extend the solution to include the following aspects to meet your security operational needs:

  • In Considerations for security operations in the cloud, we spoke about the role of ChatOps. AWS Chatbot can enable OUs to set up rules to post notifications directly into chat rooms such as Amazon Chime or Slack. You can define rules to send only certain severity notifications or findings that are important to your OU to the chat room.
  • SCPs give organizations a level of control and governance. See this blog post for some best practices for deploying SCPs, as well as example policies that could be beneficial for your organization in any model you operate in.
  • We’ve performed testing of the decentralized and hybrid models in the reference architecture within one AWS Region. Although we don’t see any reason why this solution would not work in multiple Regions, if you do operate in multiple Regions you would need to deploy the CloudFormation template in each Region that you operate in. At this stage, you can keep findings within a Region or choose to centralize across multiple Regions by sending to the single central bus in Amazon EventBridge—the flexibility is yours.
  • The decentralized and hybrid models can also be extended if you operate in multiple organizations in AWS Organizations or have standalone accounts outside of your organization that you want to monitor. Interesting use cases could be in mergers and acquisitions scenarios, when newly acquired accounts need to be monitored to understand their posture before bringing them fully into the organization.

Throughout this two-part blog series, we’ve explored the role of the Security Operations Center (SOC) function, both traditionally in an on-premises environment and in the cloud. We’ve explored different operating models, from the traditional centralized deployment to the decentralized and hybrid models. We’ve also demonstrated, with reference architectures and deployable solutions, how you can achieve the different operating models in the AWS Cloud by using native AWS services. In the end, you should choose the model that works best for your environment and the security landscape you work in.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Stuart Gregg

Stuart Gregg

Stuart enjoys providing thought leadership and being a trusted advisor to customers. In his spare time Stuart can be seen either training for an Ironman or snacking.

Author

Siva Rajamani

Siva is a Boston-based Enterprise Solutions Architect. He enjoys working closely with customers and supporting their digital transformation and AWS adoption journey. His core areas of focus are Serverless, Application Integration, and Security.

Simplify Online Analytical Processing (OLAP) queries in Amazon Redshift using new SQL constructs such as ROLLUP, CUBE, and GROUPING SETS

Post Syndicated from Satesh Sonti original https://aws.amazon.com/blogs/big-data/simplify-online-analytical-processing-olap-queries-in-amazon-redshift-using-new-sql-constructs-such-as-rollup-cube-and-grouping-sets/

Amazon Redshift is a fully managed, petabyte-scale, massively parallel data warehouse that makes it fast, simple, and cost-effective to analyze all your data using standard SQL and your existing business intelligence (BI) tools.

We are continuously investing to make analytics easy with Redshift by simplifying SQL constructs and adding new operators. Now we are adding ROLLUP, CUBE, and GROUPING SETS SQL aggregation extensions to perform multiple aggregate operations in single statement and easily include subtotals, totals, and collections of subtotals in a query.

In this post, we discuss how to use these extensions to simplify your queries in Amazon Redshift.

Solution overview

Online Analytical Processing (OLAP) is an effective tool for today’s data and business analysts. It helps you see your mission-critical metrics at different aggregation levels in a single pane of glass. An analyst can use OLAP aggregations to analyze buying patterns by grouping customers by demographic, geographic, and psychographic data, and then summarizing the data to look for trends. This could include analyzing the frequency of purchases, the time frames between purchases, and the types of items being purchased. Such analysis can provide insight into customer preferences and behavior, which can be used to inform marketing strategies and product development. For example, a data analyst can query the data to display a spreadsheet showing a company’s certain type of products sold in the US in the month of July, compare revenue figures with those for the same products in September, and then see a comparison of other product sales in the US at the same time period.

Traditionally, business analysts and data analysts use a set of SQL UNION queries to achieve the desired level of detail and rollups. However, it can be very time consuming and cumbersome to write and maintain. Furthermore, the level of detail and rollups that can be achieved with this approach is limited, because it requires the user to write multiple queries for each different level of detail and rollup.

Many customers are considering migrating to Amazon Redshift from other data warehouse systems that support OLAP GROUP BY clauses. To make this migration process as seamless as possible, Amazon Redshift now offers support for ROLLUP, CUBE, and GROUPING SETS. This will allow for a smoother migration of OLAP workloads, with minimal rewrites. Ultimately, this will result in a faster and streamlined transition to Amazon Redshift. Business and data analysts can now write a single SQL to do the job of multiple UNION queries.

In the next sections, we use sample supplier balances data from TPC-H dataset as a running example to demonstrate the use of ROLLUP, CUBE, and GROUPING SETS extensions. This dataset consists of supplier account balances across different regions and countries. We demonstrate how to find account balance subtotals and grand totals at each nation level, region level, and a combination of both. All these analytical questions can be answered by a business user by running simple single-line SQL statements. Along with aggregations, this post also demonstrates how the results can be traced back to attributes participated in generating subtotals.

Data preparation

To set up the use case, complete the following steps:

  1. On the Amazon Redshift console, in the navigation pane, choose Editor¸ then Query editor v2.

The query editor v2 opens in a new browser tab.

  1. Create a supplier sample table and insert sample data:
create table supp_sample (supp_id integer, region_nm char(25), nation_nm char(25), acct_balance numeric(12,2));

INSERT INTO public.supp_sample (supp_id,region_nm,nation_nm,acct_balance)
VALUES
(90470,'AFRICA                   ','KENYA                    ',1745.57),
(99910,'AFRICA                   ','ALGERIA                  ',3659.98),
(26398,'AMERICA                  ','UNITED STATES            ',2575.77),
(43908,'AMERICA                  ','CANADA                   ',1428.27),
(3882,'AMERICA                  ','UNITED STATES            ',7932.67),
(42168,'ASIA                     ','JAPAN                    ',343.34),
(68461,'ASIA                     ','CHINA                    ',2216.11),
(89676,'ASIA                     ','INDIA                    ',4160.75),
(52670,'EUROPE                   ','RUSSIA                   ',2469.40),
(32190,'EUROPE                   ','RUSSIA                   ',1119.55),
(19587,'EUROPE                   ','GERMANY                  ',9904.98),
(1134,'MIDDLE EAST              ','EGYPT                    ',7977.48),
(35213,'MIDDLE EAST              ','EGYPT                    ',737.28),
(36132,'MIDDLE EAST              ','JORDAN                   ',5052.87);

We took a sample from the result of the following query run on TPC-H dataset. You can use the following query and take sample records to try the SQL statement described in this post:

select s_suppkey supp_id, r.r_name region_nm,n.n_name nation_nm, s.s_acctbal acct_balance
from supplier s, nation n, region r
where
s.s_nationkey = n.n_nationkey
and n.n_regionkey = r.r_regionkey

Let’s review the sample data before running the SQLs using GROUPING SETS, ROLLUP, and CUBE extensions.

The supp_sample table consists of supplier account balances from various nations and regions across the world. The following are the attribute definitions:

  • supp_id – The unique identifier for each supplier
  • region_nm – The region in which the supplier operates
  • nation_nm – The nation in which the supplier operates
  • acct_balance – The supplier’s outstanding account balance

GROUPING SETS

GROUPING SETS is a SQL aggregation extension to group the query results by one or more columns in a single statement. You can use GROUPING SETS instead of performing multiple SELECT queries with different GROUP BY keys and merge (UNION) their results.

In this section, we show how to find the following:

  • Account balances aggregated for each region
  • Account balances aggregated for each nation
  • Merged results of both aggregations

Run the following SQL statement using GROUPING SETS:

SELECT region_nm, nation_nm, sum(acct_balance) as total_balance
FROM supp_sample
GROUP BY GROUPING SETS (region_nm, nation_nm);

As shown in the following screenshot, the result set includes aggregated account balances by region_nm, followed by nation_nm, and then both results combined in a single output.

ROLLUP

The ROLLUP function generates aggregated results at multiple levels of grouping, starting from the most detailed level and then aggregating up to the next level. It groups data by particular columns and extra rows that represent the subtotals, and assumes a hierarchy among the GROUP BY columns.

In this section, we show how to find the following:

  • Account balances for each combination of region_nm and nation_nm
  • Rolled-up account balances for each region_nm
  • Rolled-up account balances for all regions

Use the following SQL statement using ROLLUP:

SELECT region_nm, nation_nm, sum(acct_balance) as total_balance
FROM supp_sample
GROUP BY ROLLUP (region_nm, nation_nm)
ORDER BY region_nm,nation_nm;

The following result shows rolled-up values starting from each combination of region_nm and nation_nm and rolls up in the hierarchy from nation_nm to region_nm. The rows with a value for region_nm and NULL value for nation_nm represent the subtotals for the region (marked in green). The rows with NULL value for both region_nm and nation_nm has the grand total—the rolled-up account balances for all regions (marked in red).


ROLLUP is structurally equivalent to the following GROUPING SETS query:

SELECT region_nm, nation_nm, sum(acct_balance) as total_balance
FROM supp_sample
GROUP BY GROUPING SETS((region_nm, nation_nm), (region_nm), ())
ORDER BY region_nm,nation_nm;

You can rewrite the preceding ROLLUP query using GROUPING SETS. However, using ROLLUP is a much simpler and readable construct for this use case.

CUBE

CUBE groups data by the provided columns, returning extra subtotal rows representing the totals throughout all levels of grouping columns, in addition to the grouped rows. CUBE returns the same rows as ROLLUP, while adding additional subtotal rows for every combination of grouping column not covered by ROLLUP.

In this section, we show how to find the following:

  • Account balance subtotals for each nation_nm
  • Account balance subtotals for each region_nm
  • Account balance subtotals for each group of region_nm and nation_nm combination
  • Overall total account balance for all regions

Run the following SQL statement using CUBE:

SELECT region_nm, nation_nm, sum(acct_balance) as total_balance
FROM supp_sample
WHERE region_nm in ('AFRICA','AMERICA','ASIA') GROUP BY CUBE(region_nm, nation_nm)
ORDER BY region_nm, nation_nm;

In the preceding query, we added a filter to limit results for easy explanation. You can remove this filter in your test to view data for all regions.

In the following result sets, you can see the subtotals at region level (marked in green). These subtotal records are the same records generated by ROLLUP. Additionally, CUBE generated subtotals for each nation_nm (marked in yellow). Finally, you can also see the grand total for all three regions mentioned in the query (marked in red).

CUBE is structurally equivalent to the following GROUPING SETS query:

SELECT region_nm, nation_nm, sum(acct_balance) as total_balance
FROM supp_sample
WHERE region_nm in ('AFRICA','AMERICA','ASIA') -- added the filter to limit results.  You can remove this filter in your test to view data for all regions
GROUP BY GROUPING SETS((region_nm, nation_nm), (region_nm), (nation_nm), ())
ORDER BY region_nm;

You can rewrite the preceding CUBE query using GROUPING SETS. However, using CUBE is a much simpler and readable construct for this use.

NULL values

NULL is a valid value in a column that participates in GROUPING SETS, ROLLUP, and CUBE, and it’s not aggregated with the NULL values added explicitly to the result set to satisfy the schema of returning tuples.

Let’s create an example table orders containing details about items ordered, item descriptions, and quantity of the items:

-- Create example orders table and insert sample records
CREATE TABLE orders(item_no int,description varchar,quantity int);
INSERT INTO orders(item_no,description,quantity)
VALUES
(101,'apples',10),
(102,null,15),
(103,'banana',20);

--View the data
SELECT * FROM orders;

We use the following ROLLUP query to aggregate quantities by item_no and description:

SELECT item_no, description, sum(quantity)
FROM orders
GROUP BY ROLLUP(item_no, description)
ORDER BY 1,2;

In the following result, there are two output rows for item_no 102. The row marked in green is the actual data record in the input, and the row marked in red is the subtotal record added by the ROLLUP function.

This demonstrates that NULL values in input are separate from the NULL values added by SQL aggregate extensions.

Grouping and Grouping_ID functions

GROUPING indicates whether a column in the GROUP BY list is aggregated or not. GROUPING(expr) returns 0 if a tuple is grouped on expr; otherwise it returns 1. GROUPING_ID(expr1, expr2, …, exprN) returns an integer representation of the bitmap that consists of GROUPING(expr1), GROUPING(expr2), …, GROUPING(exprN).

This feature helps us clearly understand the aggregation grain, slice and dice data, and apply filters when business users are performing analysis. Also provides auditability for the generated aggregations.

For example, let’s use the preceding supp_sampe table. The following ROLLUP query utilizes GROUPING and GROUPING_ID functions:

SELECT region_nm,
nation_nm,
sum(acct_balance) as total_balance,
GROUPING(region_nm) as gr,
GROUPING(nation_nm) as gn,
GROUPING_ID(region_nm, nation_nm) as grn
FROM supp_sample
GROUP BY ROLLUP(region_nm, nation_nm)
ORDER BY region_nm;

In the following result set, the rows rolled up at nation_nm have 1 value for gn. This indicates that the total_balance is the aggregated value for all the nation_nm values in the region. The last row has gr value as 1. It indicates that total_balance is an aggregated value at region level including all the nations. The grn is an integer representation of bitmap (11 in binary translated to 3 in integer representation).

Performance assessment

Performance is often a key factor, and we wanted to make sure we’re offering most performant SQL features in Amazon Redshift. We performed benchmarking with the 3 TB TPC-H public dataset on an Amazon Redshift cluster with different sizes (5-node Ra3-4XL, 2-node Ra3-4XL, 2-node-Ra3-XLPLUS). Additionally, we disabled query caching so that query results aren’t cached. This allows us to measure the performance of the database as opposed to its ability to serve results from cache. The results were consistent across multiple runs.

We loaded the supplier, region, and nation files from the 3 TB public dataset and created a view on top of those three tables, as shown in the following code. This query joins the three tables to create a unified record. The joined dataset is used for performance assessment.

create view v_supplier_balances as
select r.r_name region_nm,n.n_name nation_nm, s.s_acctbal acct_balance
from supplier s, nation n, region r
where
s.s_nationkey = n.n_nationkey
and n.n_regionkey = r.r_regionkey;

We ran the following example SELECT queries using GROUPING SETS, CUBE, and ROLLUP, and captured performance metrics in the following tables.
ROLLUP:

SELECT region_nm, nation_nm, sum(acct_balance) as total_balance
FROM v_supplier_balances
GROUP BY ROLLUP (region_nm, nation_nm)
ORDER BY region_nm;
Cluster Run 1 in ms Run 2 in ms Run 3 in ms
5-node-Ra3-4XL 120 118 117
2-node-Ra3-4XL 405 389 391
2-node-Ra3-XLPLUS 490 460 461

CUBE:

SELECT region_nm, nation_nm, sum(acct_balance) as total_balance
FROM v_supplier_balances
GROUP BY CUBE(region_nm, nation_nm)
ORDER BY region_nm;
Cluster Run 1 in ms Run 2 in ms Run 3 in ms
5-node-Ra3-4XL 224 215 214
2-node-Ra3-4XL 412 392 392
2-node-Ra3-XLPLUS 872 798 793

GROUPING SETS:

SELECT region_nm, nation_nm, sum(acct_balance) as total_balance
FROM v_supplier_balances
GROUP BY GROUPING SETS(region_nm, nation_nm)
ORDER BY region_nm;
Cluster Run 1 in ms Run 2 in ms Run 3 in ms
5-node-Ra3-4XL 210 198 198
2-node-Ra3-4XL 345 328 328
2-node-Ra3-XLPLUS 675 674 674

When we ran the same set of queries for ROLLUP and CUBE and ran with UNION ALL, we saw better performance with ROLLUP and CUBE functionality.

Cluster CUBE (run in ms) ROLLUP (run in ms) UNION ALL (run in ms)
5-node-Ra3-4XL 214 117 321
2-node-Ra3-4XL 392 391 543
2-node-Ra3-XLPLUS 793 461 932

Clean up

To clean up your resources, drop the tables and views you created while following along with the example in this post.

Conclusion

In this post, we talked about the new aggregated extensions ROLLUP, CUBE, and GROUPING SETS added to Amazon Redshift. We also discussed general uses cases, implementation examples, and performance results. You can simplify your existing aggregation queries using these new SQL aggregation extensions and use them in future development for building more simplified, readable queries. If you have any feedback or questions, please leave them in the comments section.


About the Authors

Satesh Sonti is a Sr. Analytics Specialist Solutions Architect based out of Atlanta, specialized in building enterprise data platforms, data warehousing, and analytics solutions. He has over 16 years of experience in building data assets and leading complex data platform programs for banking and insurance clients across the globe.

Yanzhu Ji is a Product Manager on the Amazon Redshift team. She worked on the Amazon Redshift team as a Software Engineer before becoming a Product Manager. She has a rich experience of how the customer-facing Amazon Redshift features are built from planning to launching, and always treats customers’ requirements as first priority. In her personal life, Yanzhu likes painting, photography, and playing tennis.

Dinesh Kumar is a Database Engineer with more than a decade of experience working in the databases, data warehousing, and analytics space. Outside of work, he enjoys trying different cuisines and spending time with his family and friends.

Introducing Client-side Evaluation for Amazon CloudWatch Evidently

Post Syndicated from Cole Thienes original https://aws.amazon.com/blogs/architecture/introducing-client-side-evaluation-for-amazon-cloudwatch-evidently/

Amazon CloudWatch Evidently enables developers to test new features on a small percentage of traffic and gauge the outcome before rolling it out to the rest of their users. Evidently feature flags are defined ahead of your release and, at runtime, your application code queries a remote service to determine whether to show the new feature to a given user. The remote call to fetch feature flags for a user is susceptible to network latency, adding several hundred milliseconds of delay in bad cases. Any additional latency added to fetching feature flags can directly impact the speed of a web page, where milliseconds matter. Our solution: client-side evaluation for Amazon CloudWatch Evidently. With client-side evaluation, developers can significantly decrease latency by fetching feature flags locally and avoiding network overhead altogether.

The term “client-side” does not refer to the browser in this case, but the operation taking place on your container application rather than through a remote API call. This removes the need for a network call by fetching feature flags for a user from the AWS AppConfig agent—a sidecar container running alongside your container application backend. The agent enables container runtimes to leverage AWS AppConfig, a service allowing customers to change the way an application behaves while running without deploying new code. In this post, we’ll walk through the solution architecture and how to instrument client-side evaluation in an Amazon Elastic Container Service (Amazon ECS) application.

Overview of solution

Figure 1 illustrates how client-side evaluation works in an application running on Amazon ECS. The webpage makes a call to the webpage backend to determine which website features to show an end-user. Let’s explore how this works.

High-level architecture of Client-side Evaluation for Amazon CloudWatch Evidently

Figure 1. High-level architecture of client-side evaluation for Amazon CloudWatch Evidently

  1. Create an Evidently project, feature, and launch through the AWS Console Mobile Application, API, or AWS CloudFormation.
  2. Create an Amazon ECS task for the backend application container and attach an AWS AppConfig agent container to the task. At runtime, the application container will invoke the EvaluateFeature API to fetch feature flags. Without client-side evaluation, this API call would perform a remote call to the Evidently cloud service.
  3. With client-side evaluation, the API call is made from the application container to the AWS AppConfig agent container on localhost, short-circuiting the network overhead.
  4. Evidently maintains a synchronized copy of the Evidently features in an AWS AppConfig configuration within your AWS account. When subsequent changes are made to the features, the configuration is updated (usually within a minute).
  5. When the backend application initializes, the agent fetches the necessary configuration profile and caches it, polling periodically to refresh the cache. When the AWS AppConfig agent is invoked from the backend application, it evaluates the requested feature flag using the cached data.
  6. After each successful EvaluateFeature call, a transaction record is generated, called an evaluation event. This useful bookkeeping mechanism helps developers view data to tell which of their users saw what feature and when. As the evaluation events are generated, they are placed in a buffer within the agent. Once the buffer reaches a certain size or age, events in the buffer are uploaded to Evidently via the PutProjectEvents API.
  7. The evaluation events are then available for offline analysis in developer-configured storage, including CloudWatch Logs, Amazon Simple Storage Service (Amazon S3), and CloudWatch Metrics.

Walkthrough

Let’s take a practical example to demonstrate client-side evaluation. I have a simple webpage with a search bar on it. I’ve implemented a newer, fancier search bar, but I only want to show it to 10 percent of my visitors to make sure it doesn’t cause issues on my existing webpage before rolling it out to everyone, as in Figure 2.

Web page experience where 10% of users see the new search bar

Figure 2. A webpage experience where 10% of users see the new search bar

We could set up the necessary AWS resources by hand, but let’s use a pre-built AWS Cloud Development Kit (AWS CDK) example to save time. The sample code for this example is available on GitHub. Here are the high-level steps:

  1. Provision the infrastructure. The infrastructure will consist of:
    • An ECS service with a Virtual Private Cloud (Amazon VPC) to serve as our backend application and return the search bar variation
    • An Evidently launch to split the traffic between the two search bars
    • An AWS AppConfig environment, which the AWS AppConfig agent will fetch Evidently data from
  2. Test our webpage. Once our code is deployed, we will visit our webpage to fetch feature flags using client-side evaluation.
  3.  Clean up by removing our infrastructure.

Prerequisites

Steps

Clone the repository

First, clone the official AWS CDK example repository:

git clone https://github.com/aws-samples/aws-cdk-examples

The repository has many examples for setting up AWS infrastructure in CDK. Let’s go to a client-side evaluation example.

Code explanation

Let’s take a look at the code example. When we visit our web page, a request will be routed to our application deployed on AWS Fargate, which allows us to run containers directly using ECS without having to manage Elastic Compute Cloud (Amazon EC2) instances. The application code is written in Node.js with Typescript and leverages the Express framework:

<p><code>// local-image/app.ts</code></p><p><code>import * as express from 'express';</code><br /><code>import {Evidently} from '@aws-sdk/client-evidently';</code></p><p><code>const app = express();</code></p><p><code>const evidently = new Evidently({</code><br /><code>    endpoint: 'http://localhost:2772',</code><br /><code>    disableHostPrefix: true</code><br /><code>});</code></p><p><code>app.get("/", async (_, res) =&gt; {</code><br /><code>    try {</code><br /><code>        console.time('latency')</code><br /><code>        const evaluation = await evidently.evaluateFeature({</code><br /><code>            project: 'WebPage',</code><br /><code>            feature: 'SearchBar',</code><br /><code>            entityId: 'WebPageVisitor43'</code><br /><code>        })</code><br /><code>        console.timeEnd('latency')</code><br /><code>        res.send(evaluation.variation)</code><br /><code>    } catch (err: any) {</code><br /><code>        console.timeEnd('latency')</code><br /><code>        res.send(err.toString())</code><br /><code>    }</code><br /><code>});</code></p>

The container application will invoke the EvaluateFeature API using the AWS SDK for Javascript and return the search bar variation, either the old or new search bar. Here we also log the latency of the operation. The EvaluateFeature request is forwarded to the endpoint we configure for the Evidently client: http://localhost:2772. This is the local address where the AWS AppConfig agent can be reached. To make this possible, we add the AWS AppConfig agent as a container to the Amazon ECS task definition:

// index.ts

service.taskDefinition.addContainer('AppConfigAgent', {
    image: ecs.ContainerImage.fromRegistry('public.ecr.aws/aws-appconfig/aws-appconfig-agent:2.x'),
    portMappings: [{
        containerPort: 2772
    }]
})

We also need to set up an AppConfig environment for the Evidently project. This tells Evidently where to create the configuration to keep a synchronized copy of the features in the project:

// index.ts

const application = new appconfig.CfnApplication(this,'AppConfigApplication', {
    name: 'MyApplication'
});

const environment = new appconfig.CfnEnvironment(this, 'AppConfigEnvironment', {
    applicationId: application.ref,
    name: 'MyEnvironment'
});

const project = new evidently.CfnProject(this, 'EvidentlyProject', {
    name: 'WebPage',
    appConfigResource: {
        applicationId: application.ref,
        environmentId: environment.ref
    }
});

Finally, we set up an Evidently feature and launch that ensures only 10 percent of traffic receives the new search bar:

// index.ts

const launch = new evidently.CfnLaunch(this, 'EvidentlyLaunch', {
  project: project.name,
  name: 'MyLaunch',
  executionStatus: {
    status: 'START'
  },
  groups: [
    {
      feature: feature.name,
      variation: OLD_SEARCH_BAR,
      groupName: OLD_SEARCH_BAR
    },
    {
      feature: feature.name,
      variation: NEW_SEARCH_BAR,
      groupName: NEW_SEARCH_BAR
    }
  ],
  scheduledSplitsConfig: [{
    startTime: '2022-01-01T00:00:00Z',
    groupWeights: [
      {
        groupName: OLD_SEARCH_BAR,
        splitWeight: 90000
      },
      {
        groupName: NEW_SEARCH_BAR,
        splitWeight: 10000
      }
    ]
  }]
})

We start the launch immediately by setting executionStatus to START and startTime to a timestamp in the past. If you want to wait to show the new search bar, we can specify a future start time.

Install dependencies

Install the necessary Node modules:

npm install

Build and deploy

Build the AWS CDK template from the source code:

npm run build

Before deploying the app:

  1. Ensure that you set up AWS credentials in your environment.
  2. The AWS CDK Toolkit is bootstrapped in your AWS account.
  3. Confirm the max number of VPCs has not been reached in your AWS account; the Amazon ECS service will deploy an Amazon VPC.

After that, you can deploy the AWS CDK template to your AWS account:

cdk deploy

Test the webpage

After the previous step, you should see the following output in your console:

Console output showing a successful CDK deployment

Figure 3. Console output showing a successful AWS CDK deployment

In your browser, visit the URL specified by the FargateServiceServiceURL output above and you will see oldSearchBar. We can visit our CloudWatch Logs from the Amazon ECS task to see our application logs. Go to the AWS console and visit the CloudWatch log groups page and visit the log group with the prefix EvidentlyClientSideEvaluationEcs. There, we can see that fetching feature flags took under two milliseconds, as in Figure 4.

CloudWatch Logs for the Amazon ECS task showing an EvaluateFeature latency of 1.238 milliseconds

Figure 4. CloudWatch Logs for the Amazon ECS task showing an EvaluateFeature latency of 1.238 milliseconds

Additionally, we can see how visitors have seen each version of the search bar. On the AWS console, visit the CloudWatch metrics page and see the Evidently metrics under All > Evidently > Feature, Project, Variation, as in Figure 5:

CloudWatch metrics showing the VariationCount: the number of times each feature flag variation was fetched

Figure 5. CloudWatch metrics showing the VariationCount (the number of times each feature flag variation was fetched)

We can increase or decrease the percentage of visitors seeing the new search bar at any time. On the AWS console, go to the CloudWatch Evidently page and go to Projects > WebPage > Launches > MyLaunch > Modify launch traffic and adjust the Traffic percentage, as in Figure 6.

Adjusting the traffic percentage of an Evidently launch

Figure 6. Adjusting the traffic percentage of an Evidently launch

Cleaning up

To avoid incurring future charges, delete the resources. Let’s run:

cdk destroy

You can confirm the removal by going into CloudFormation and confirming the resources were deleted.

Conclusion

In this blog post, we learned how to set up a web page backend in Amazon ECS with client-side evaluation for Amazon CloudWatch Evidently. We easily deployed the example CloudFormation stack with AWS CDK Toolkit. Then we visited the example webpage and demonstrated the improved speed of fetching feature flags with client-side evaluation. If you’re interested in using client-side evaluation with AWS Lambda instead of Amazon ECS, check out this AWS CDK example.