Tag Archives: AWS Lambda

Patch perfect: Automating Amazon Redshift patch testing

Post Syndicated from Eva Donaldson original https://aws.amazon.com/blogs/big-data/patch-perfect-automating-amazon-redshift-patch-testing/

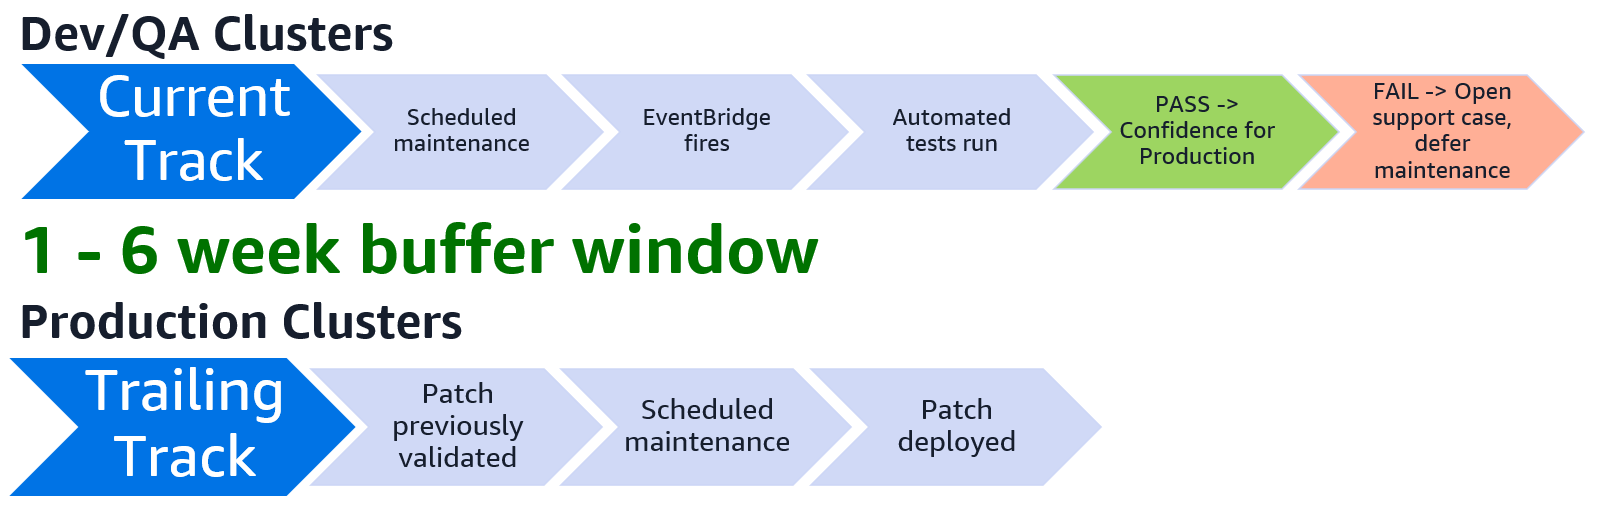
Amazon Redshift continuously innovates to deliver improved performance and advanced features. In some releases, Amazon Redshift patches might introduce behavior changes. Testing patches in a non-production environment confirms that production workloads continue to function and you can maintain your applications’ service level agreements. As a best practice, keep Dev/QA clusters on the Current patch track and Production on the Trailing track. Test on Dev/QA when a patch lands, allowing 1–6 weeks of review before the scheduled production deployment.

In this post, we demonstrate an automated test suite that validates your Amazon Redshift cluster automatically after any patch, reboot, or modification. It uses standard drivers against real workload patterns to provide a verified gate between a patch landing and that patch reaching production.

Architecture

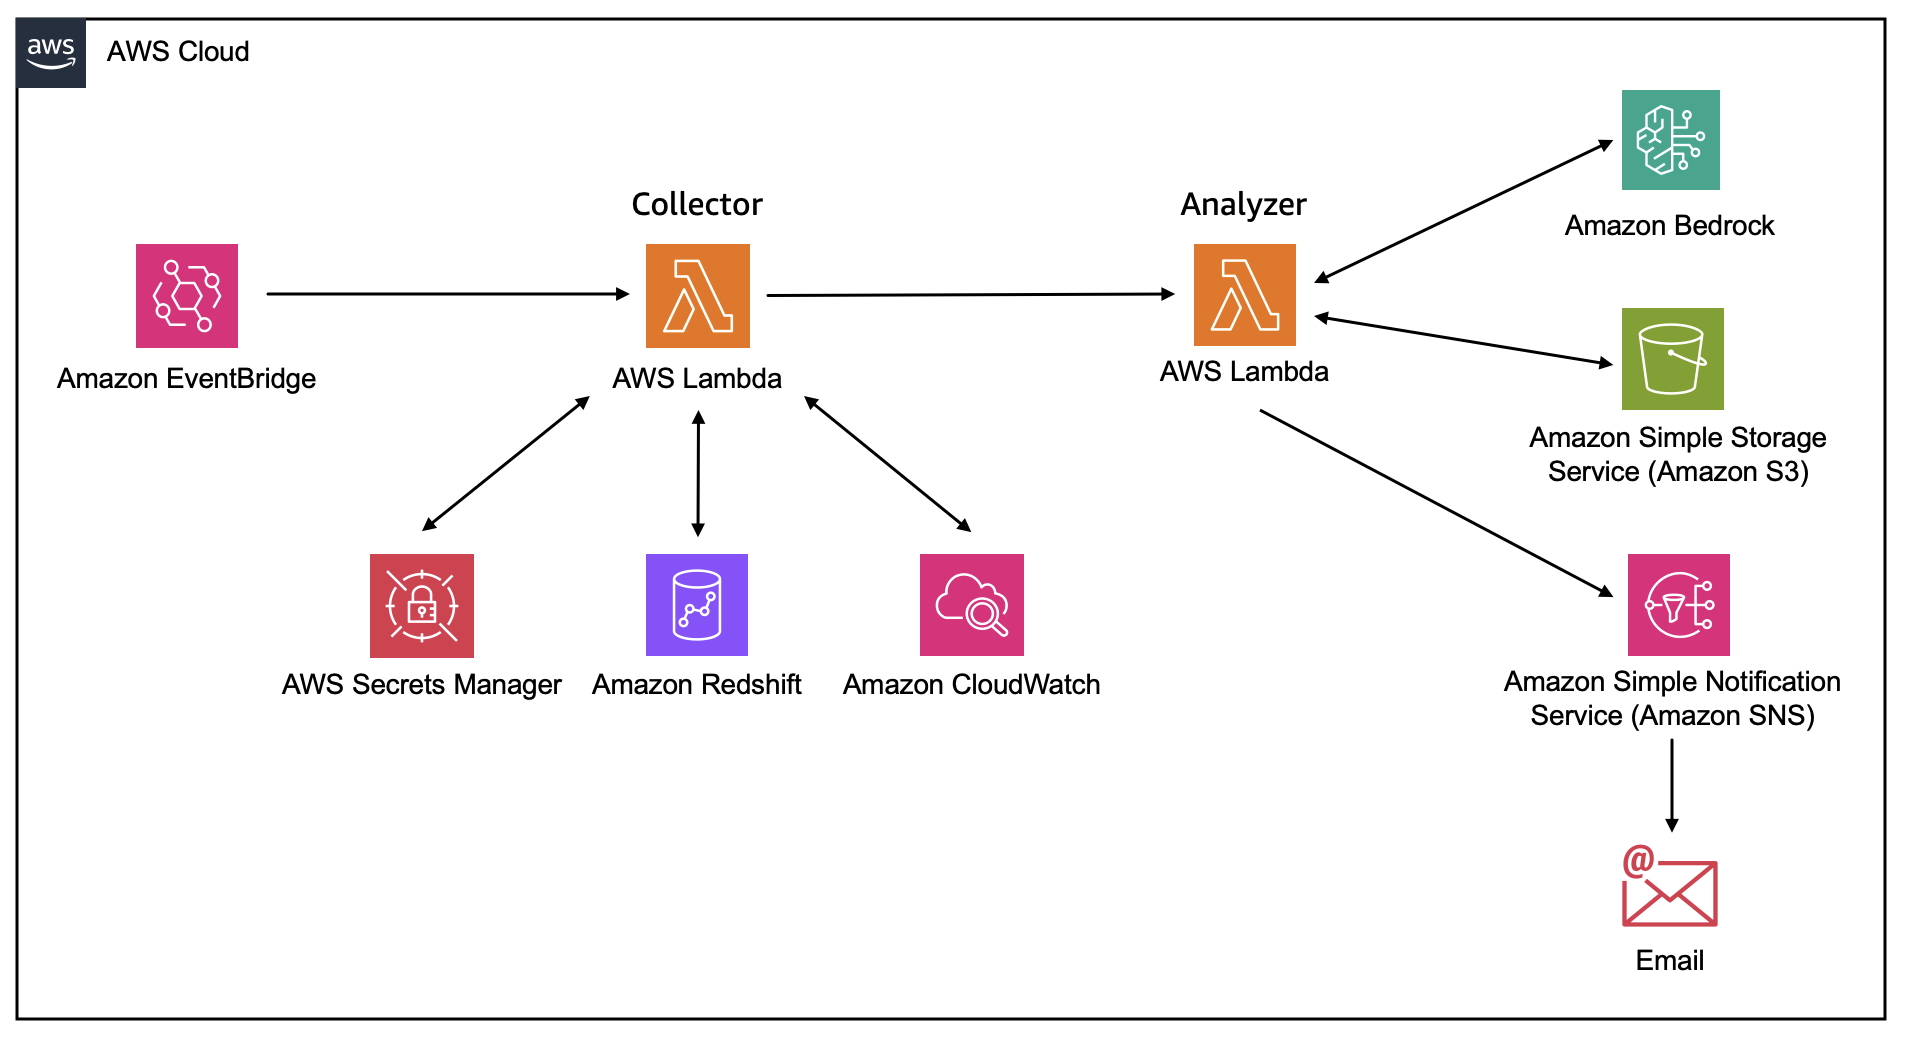
The solution uses native AWS services to create an automated validation pipeline.

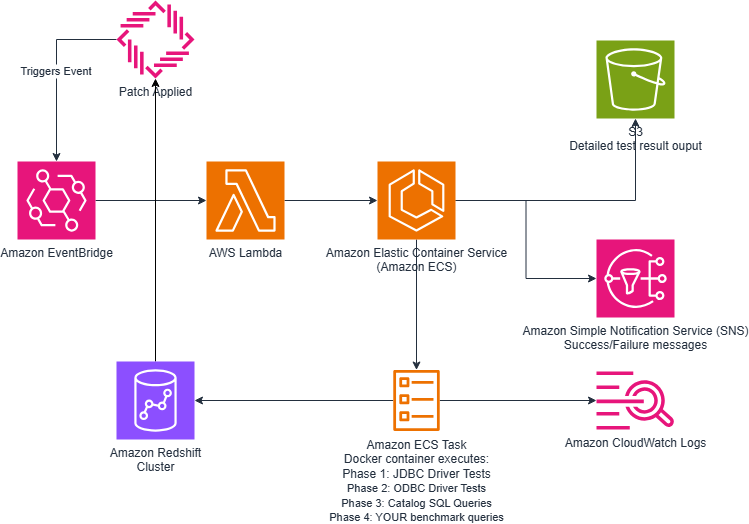
Architecture diagram of the patch testing pipeline: Amazon EventBridge triggers AWS Lambda, which runs an AWS Fargate task that tests the cluster and reports to Amazon S3 and Amazon SNS

Figure 1 — High-level architecture diagram

Process overview showing the four stages: event detection, orchestration, test execution, and reporting

Figure 2 — Process overview

  1. Event Detection: When your Amazon Redshift cluster receives a patch, reboot, or modification, the Amazon Redshift cluster event notifications fire. Amazon EventBridge rules match these events automatically.
  2. Orchestration: A lightweight AWS Lambda function receives the event from the Amazon EventBridge rule and launches an AWS Fargate task. The task runs in a subnet within the same Amazon Virtual Private Cloud (VPC) as your Amazon Redshift cluster, giving the test runner direct network connectivity to the cluster endpoint.
  3. Test Execution: A Docker container runs a comprehensive test suite in four phases:
    • JDBC Driver Tests – Validates the official Amazon Redshift JDBC driver, testing DatabaseMetaData API calls, connection handling, and queries that tools like SQL Workbench/J depend on.
    • ODBC Driver Tests – Validates the PostgreSQL ODBC driver with SQLTables, SQLColumns, and other ODBC API calls that RStudio and similar tools use.
    • Catalog SQL Queries – Runs approximately 35 queries against pg_catalog, information_schema, and svv_* views, organized by client (SQL Workbench, DBeaver, RStudio, JDBC metadata API).
    • Performance Benchmarks – Executes your custom workload queries and compares execution time against known baselines, flagging regressions. For convenience, the solution includes sample queries to be replaced with performance validation queries from your workloads.
  4. Reporting: Detailed JSON results land in Amazon Simple Storage Service (Amazon S3) for historical analysis. An Amazon Simple Notification Service (Amazon SNS) notification sends your team an email immediately with a pass/fail summary. Full JSON results are written to Amazon S3 with timing data for every individual query, row counts, error details, and the Amazon EventBridge event that triggered the run. If tests fail, you have specific, actionable evidence (which queries broke, which drivers failed, which benchmarks regressed) to open a support case requesting a rollback and defer maintenance until the case is resolved. When tests succeed, you can move forward with confidence to production.

For real-time feedback while the tests are running, a quick command tells you the current state:

aws lambda invoke --function-name my-redshift-tests-trigger \
--payload '{}' --cli-binary-format raw-in-base64-out /dev/stdout

What gets tested

The test suite covers two critical areas: client tool compatibility and query performance.

Client compatibility queries

The test suite replicates the connection behavior of popular SQL clients by issuing the same metadata API calls and queries they perform when connecting to your cluster.

Client What’s tested
SQL Workbench/J Connection queries, schema browsing, metadata enumeration
DBeaver Database object discovery, catalog traversal
RStudio (DBI/odbc) ODBC-specific catalog queries, column type mapping
JDBC Metadata API getTables(), getColumns(), getPrimaryKeys(), and other DatabaseMetaData method equivalents

The package contains the exact queries these clients execute upon connection.

Performance regression detection

The benchmark phase of the suite automatically detects whether it has been run before. On the first execution, it captures baseline query execution times as the “known good” state for your pre-patch environment. On every subsequent run, it compares current query timings against the stored baseline and flags any regressions. If a query that previously completed in 2 seconds now takes 15, the report calls it out immediately. This phase is designed to test your most performance-sensitive queries.

Prerequisites

Before deploying, make sure your environment meets the following requirements:

Docker installed. Consider building the image with AWS CloudShell, which comes with Docker pre-installed. You can do this either by uploading the customized repo to Amazon S3 and then downloading it to AWS CloudShell, or by cloning and customizing the repo directly within AWS CloudShell.

Getting started

The full solution is available on GitHub. It includes the AWS CloudFormation template, Docker build scripts, test suite, and documentation.

Clone the GitHub repo, customize it for your workload, deploy it against a Dev/QA cluster.

Detailed instructions are included in the package README.md. Reference those for deployment.

Step 1: Clone the repo

Clone the GitHub repo.

Step 2: Customize the scripts for your environment

The test suite ships with comprehensive default queries. After cloning and before deployment, edit the scripts as described in the following sections for each phase.

Add your performance-critical queries

Edit bundle/run_tests.py and replace the example queries with queries where performance is critical:

BENCHMARK_QUERIES = {
    "daily_patient_summary": """
SELECT department, COUNT(DISTINCT patient_id), AVG(los_days)
FROM clinical.encounters
WHERE admit_date >= CURRENT_DATE - 30
GROUP BY 1
""",
    "revenue_rollup": """
SELECT payer_type, SUM(total_charges)
FROM billing.claims
WHERE service_date >= DATE_TRUNC('month', CURRENT_DATE)
GROUP BY 1
""",
}

Add client-specific catalog queries

If your team uses custom views or schemas, add them to bundle/client_catalog_queries.py:

"custom_view_check": {
    "description": "Verify our reporting view works after patching",
    "sql": "SELECT * FROM analytics.monthly_kpis LIMIT 10",
},

Step 3: Build the Docker image

Execute build-image.sh, which creates an Amazon ECR repository, builds the Docker image (with JDBC and ODBC drivers bundled), and pushes it, outputting the image URI for the next step.

# Upload project to S3, then build in CloudShell
./build-image.sh --stack-name my-redshift-tests

Step 4: Deploy the stack

Use the AWS Command Line Interface (AWS CLI) to deploy the AWS CloudFormation stack with your environment-specific parameters. The stack creates the required components: Amazon Elastic Container Service (Amazon ECS) cluster, AWS Fargate task definition, security groups, VPC endpoints (to keep AWS Secrets Manager and Amazon SNS traffic off the NAT gateway), Amazon S3 bucket, Amazon SNS topic, AWS Lambda trigger, and Amazon EventBridge rules.

aws cloudformation deploy \
--template-file template.yaml \
--stack-name my-redshift-tests \
--parameter-overrides \
RedshiftSecretArn=arn:aws:secretsmanager:... \
RedshiftHost=my-cluster.xxxx.us-east-2.redshift.amazonaws.com \
RedshiftClusterIdentifier=my-cluster \
VpcId=vpc-xxxxxxxx \
VpcSubnetIds=subnet-aaa,subnet-bbb \
RedshiftSecurityGroupId=sg-xxxxxxxx \
EcrImageUri=123456789012.dkr.ecr.us-east-2.amazonaws.com/my-redshift-tests-runner:latest \
[email protected] \
--capabilities CAPABILITY_NAMED_IAM

Key takeaways

Here are the core principles that make automated patch testing effective:

  1. Dev/QA on Current track, Production on Trailing: This separation creates the buffer window between when a patch is available and when it reaches production. Without it, there’s no opportunity to catch regressions before they affect users.
  2. Automate the validation: The track split is most effective if the test suite runs after every patch. Event-driven automation helps confirm no patch goes untested during the buffer window.
  3. Test with real drivers: Simulated queries aren’t sufficient. The test suite exercises the Amazon Redshift JDBC and PostgreSQL ODBC drivers that your SQL clients depend on. This validates the same code paths your tools use in production.
  4. Event-driven, not scheduled: Tests run the moment a patch is applied. They don’t run on a fixed cron schedule. Patch applied, then test executed, then results delivered in minutes.
  5. Low operational overhead, minimal cost: The entire solution is serverless (AWS Lambda and AWS Fargate). There are no instances to manage and no agents to install. The Fargate task spins up only when a patch event fires, runs the test suite, and shuts down. You pay only for the compute each test run consumes.

Clean up

When you no longer need the automated test suite, delete the associated resources so you don’t incur ongoing costs.

  1. Delete any created prerequisites, if not needed.
    1. Amazon Redshift cluster (removes the managed secret).
    2. NAT gateway.
    3. VPC.
  2. Empty the Amazon S3 results bucket (AWS CloudFormation cannot delete non-empty buckets).
  3. Delete the image you installed in the Amazon ECR repository in step 1 of getting started.
  4. Delete the AWS CloudFormation stack to remove the Amazon ECS cluster, AWS Fargate task definition, security groups, VPC endpoints, Amazon S3 bucket, Amazon SNS topic, AWS Lambda function, and Amazon EventBridge rules created by the deployment.
    aws cloudformation delete-stack --stack-name my-redshift-tests

Conclusion

Automated patch testing ensures consistent and predictable performance of your production workloads. By deploying Dev/QA clusters on the Current track with event-driven validation, you gain weeks of advance notice before patches reach production. The solution presented here provides comprehensive testing of JDBC drivers, ODBC drivers, catalog queries, and performance benchmarks. It requires zero manual intervention. Deploy it once, customize it for your workload, and gain confidence that the next Amazon Redshift patch will be validated before it matters.

To learn more about Amazon Redshift, explore the following resources:


About the author

Eva Donaldson

Eva Donaldson

Eva is a Senior Technical Account Manager (TAM) at AWS, specializing in Healthcare & Life Sciences customers. With 20+ years of experience as a data architect, engineer, and team manager, she focuses on designing automated data platforms and solutions that solve real business problems.

Eliminating Java cold starts with AWS Lambda Managed Instances

Post Syndicated from Jay Colodner original https://aws.amazon.com/blogs/compute/eliminating-java-cold-starts-with-aws-lambda-managed-instances/

A single cold start can push your Java Lambda function’s response time from milliseconds to seconds, enough to violate your p99 SLA, timeout a downstream service, and page your on-call. The Java Virtual Machine (JVM) performs best in long-running processes. Its Just-In-Time (JIT) compiler progressively optimizes code over thousands of invocations. Standard serverless execution environments recycle before the JVM reaches peak performance. This creates a tradeoff for latency-sensitive applications between cold-start penalties and runtime optimizations. For production services with p99 service level agreement (SLA) requirements, a single 14-second cold start spike can violate response time guarantees. It triggers downstream timeouts and degrades customer experience.

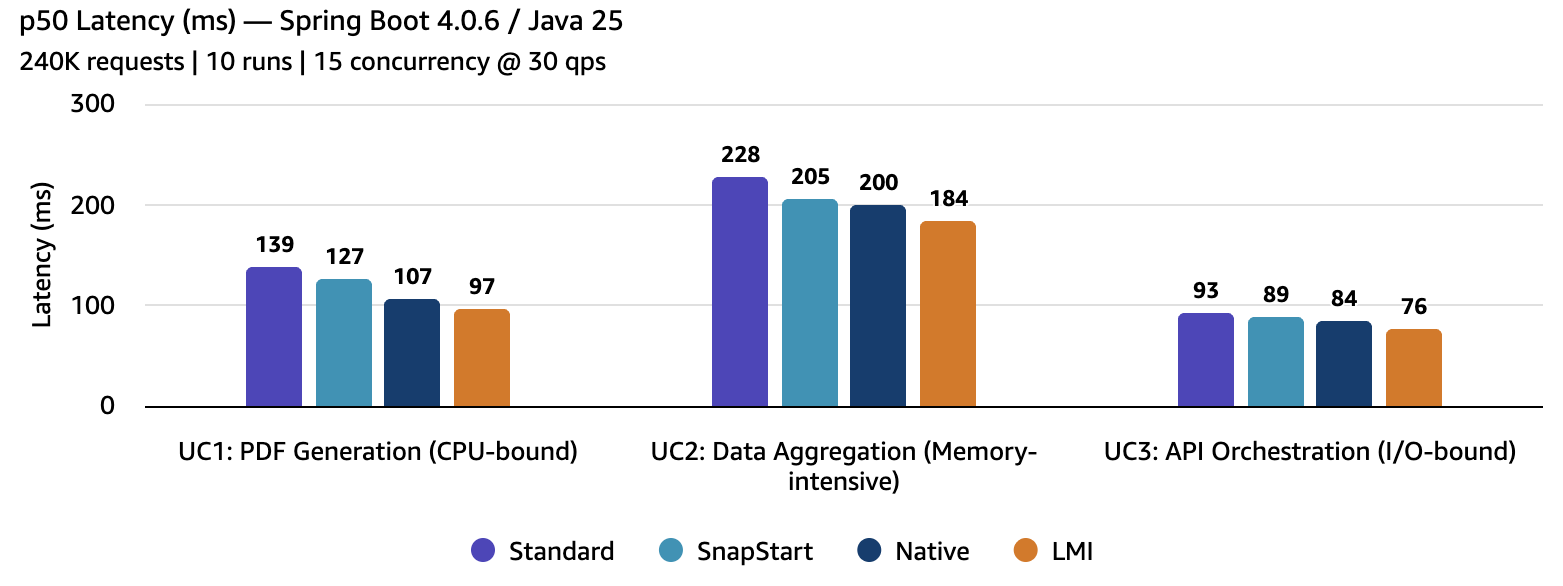
AWS Lambda Managed Instances changes this equation. As a capability of AWS Lambda, Managed Instances runs your functions on managed Amazon Elastic Compute Cloud (Amazon EC2) instances in your account and maintains JVM persistence across invocations. Connection pools, class hierarchies, and heap state persist across thousands of requests. This allows the JIT C2 compiler to complete optimizations like method inlining, escape analysis, and loop unrolling. The result: 18 to 30% better median latency and 3 to 30x better tail latency compared to Standard Lambda, as the benchmarks in this post demonstrate.

This post benchmarks four Java deployment modes across three workload types using 240,000 requests. The modes compared are Standard Lambda, AWS Lambda SnapStart, GraalVM Native Image, and Lambda Managed Instances. The workload types are CPU-bound, I/O + computation, and I/O-bound. This post presents benchmark results demonstrating Managed Instances delivering 30% better median latency and removing multi-second cold-start spikes on CPU-bound work after JIT warmup. It explains why these gains occur, maps each deployment mode to specific traffic patterns and cold-start tolerance requirements, and provides a decision framework for selecting the right approach for your workload.

Benchmarking setup

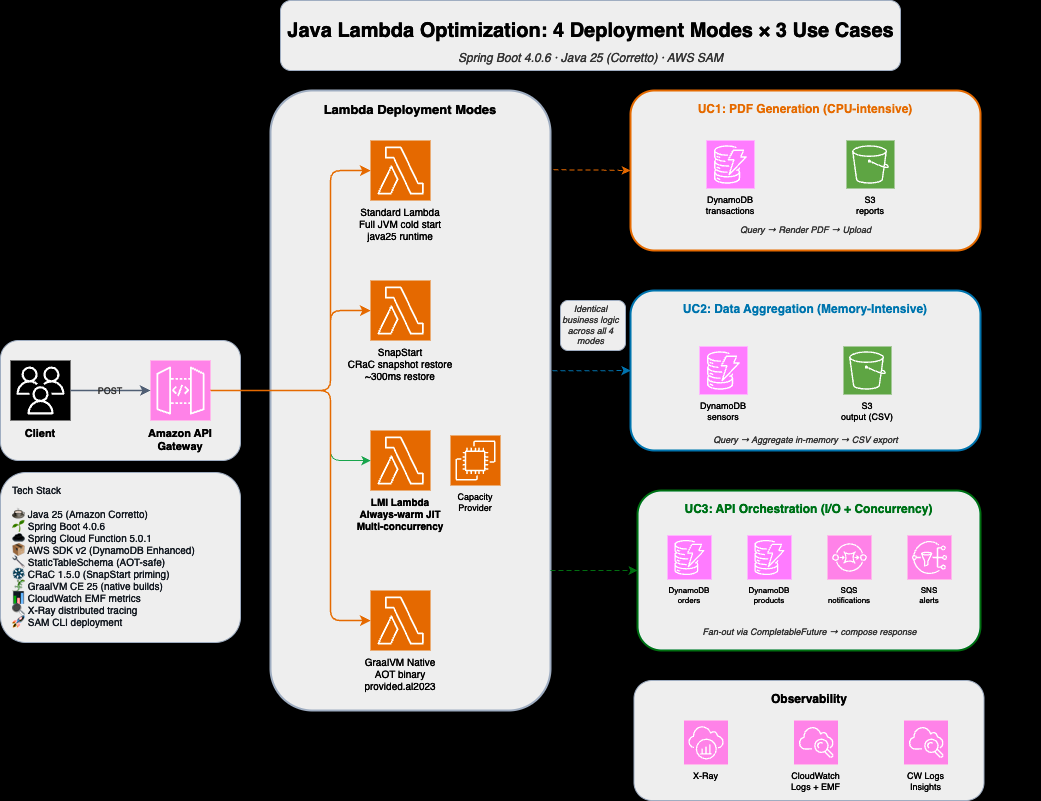
The benchmark runs all four deployment modes with identical Spring Boot 4.0.6 applications on Java 25 and AWS SDK v2. This configuration verifies fair comparison across modes. We tested three workloads: UC1 (PDF generation, CPU-bound), UC2 (data aggregation, I/O + computation), and UC3 (API orchestration, I/O-bound). The benchmark sends 240,000 requests using Artillery load testing at 33 RPS. Standard Lambda, SnapStart, and Native Lambda use 1024 MB (1 vCPU). Managed Instances uses c7i.xlarge instances with 2048 MB memory. Concurrency is tuned per workload (UC1=3, UC2=5, UC3=10) based on load testing to avoid thread contention. The benchmark measures p50, p99, and maximum latency across 10 runs of 2,000 requests each, with 5-minute cool-down between runs. The benchmark tracks JIT compilation metrics via Amazon CloudWatch Embedded Metrics Format. You can validate these results against Amazon API Gateway access logs, which confirm a <0.1% error rate. The GitHub repository contains complete source code, AWS Serverless Application Model (AWS SAM) templates, load scripts, and raw data. Performance claims in this post reference data from this benchmark methodology.

Figure 1 presents the architecture for all four deployment modes running in parallel against shared backend services.

Architecture diagram showing all four Lambda deployment modes (Standard, SnapStart, GraalVM Native, Managed Instances) running in parallel against shared backend services including DynamoDB, S3, SQS, and SNS

To reproduce these benchmarks or deploy the sample applications, refer to the GitHub repository. The repository contains complete SAM templates, Artillery load configurations, deployment instructions, and cleanup commands. This post focuses on benchmark results and analysis. The benchmark used the following tools and services:

Observing max latency

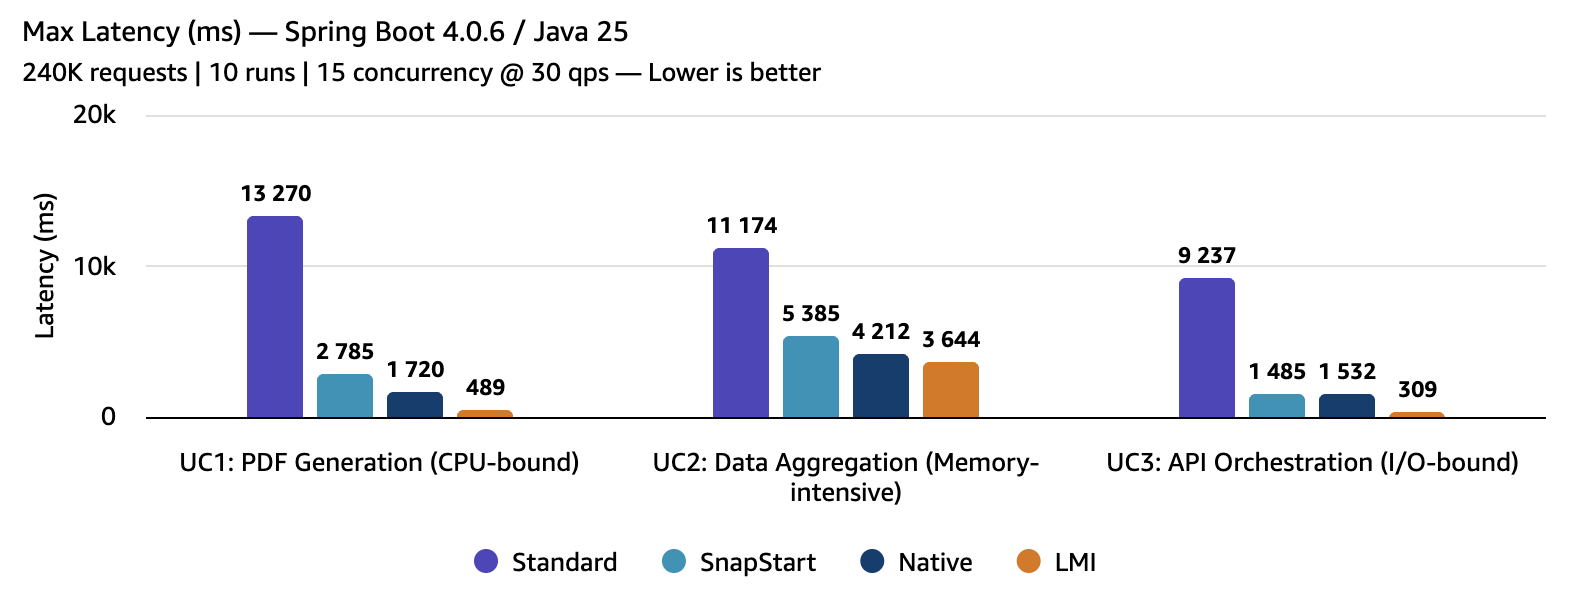
Managed Instances removes the extreme tail spikes characteristic of cold starts. Managed Instances delivers 27x faster maximum latency on CPU-bound workloads (UC1: 489 ms vs. 13,270 ms Standard). Mixed I/O + compute workloads see a 3x improvement (UC2: 3,644 ms vs. 11,174 ms Standard). I/O-bound workloads improve 30x (UC3: 309 ms vs. 9,237 ms Standard). We measured all results using the methodology described in Benchmarking setup.

Bar chart comparing maximum latency across Standard Lambda, SnapStart, GraalVM Native, and Managed Instances for three workload types

The Standard Lambda 13-second maximum on UC1 represents a full cold start. That cold start includes JVM boot, Spring context initialization, Amazon DynamoDB client setup, and the first PDF render. SnapStart reduces this to under 3 seconds by restoring from a Firecracker microVM snapshot. However, the restore process plus re-initialization of resources that cannot be checkpointed (network connections, random number generators) still adds latency. GraalVM Native starts in under 2 seconds because the ahead-of-time (AOT) compiled binary skips JVM boot entirely. The Managed Instances maximum of 487 ms is not a cold start; it’s the slowest warm request across 20,000 invocations. For production SLAs, a 14-second cold start spike on Standard Lambda violates most requirements, while Managed Instances removes that spike entirely.

Observing median latency (p50)

Lambda Managed Instances delivered the lowest median latency across all three workloads. Results demonstrate 30% faster median latency on CPU-bound workloads (UC1: 97 ms vs. 139 ms Standard). Mixed I/O + compute achieves a 19% improvement (UC2: 184 ms vs. 228 ms Standard). I/O-bound workloads improve 18% (UC3: 76 ms vs. 93 ms Standard).

Bar chart comparing median (p50) latency across Standard Lambda, SnapStart, GraalVM Native, and Managed Instances for three workload types

The improvement scales with CPU intensity because the JIT C2 compiler on persistent Managed Instances optimizes hot code paths that short-lived serverless environments never reach. On CPU-bound workloads (UC1), the JIT compiler has more opportunity to optimize tight loops in PDF rendering. On I/O-bound workloads (UC3), network latency to Amazon DynamoDB, Amazon SQS, and Amazon SNS dominates the request duration, so JIT optimization provides smaller gains.

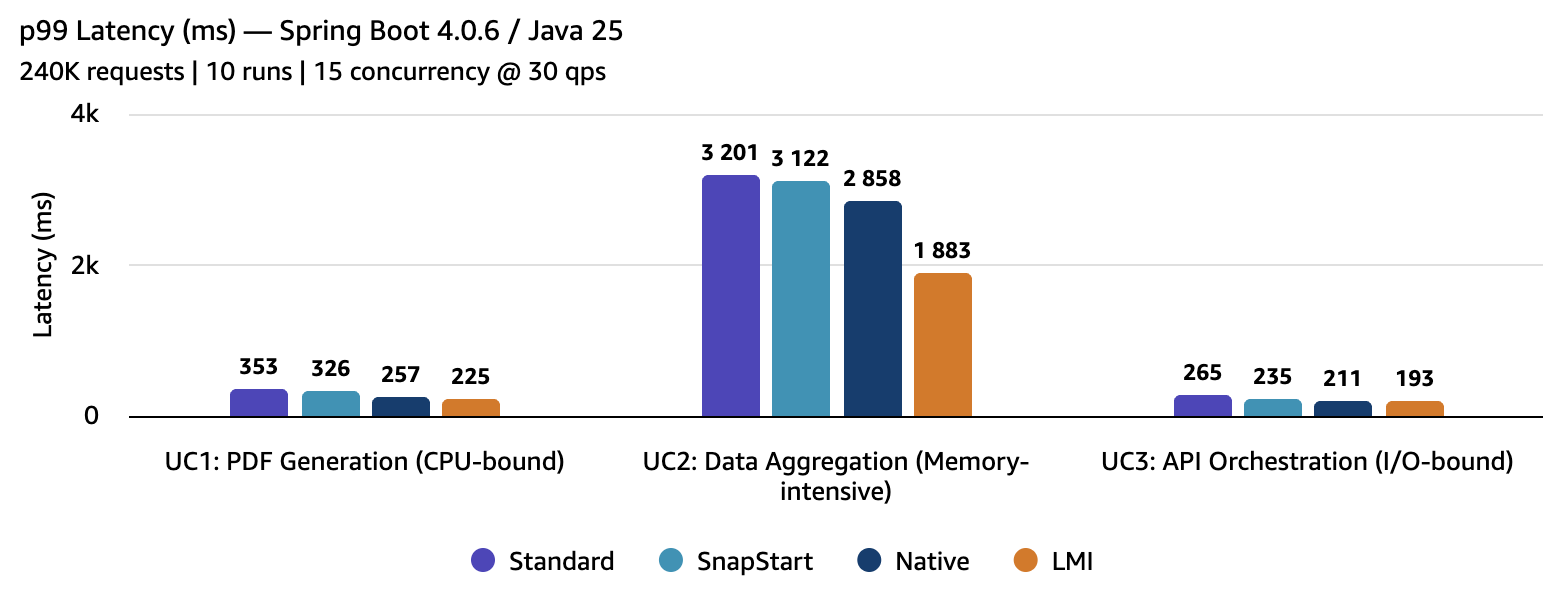
Observing tail latency (p99)

Managed Instances showed even larger improvements at the tail of the latency distribution. The p99 improves 36% on CPU-bound workloads (UC1: 225 ms vs. 353 ms Standard). Mixed I/O + compute achieves a 41% improvement (UC2: 1,883 ms vs. 3,201 ms Standard). I/O-bound workloads improve 27% (UC3: 193 ms vs. 265 ms Standard).

Bar chart comparing p99 tail latency across Standard Lambda, SnapStart, GraalVM Native, and Managed Instances for three workload types

UC2 showed the largest p99 improvement (41%) because data aggregation combines DynamoDB queries, returning hundreds of records with in-memory statistical computation and Amazon S3 uploads. Standard Lambda environments that haven’t fully warmed their JIT produce significantly slower responses at the tail. The persistent JIT optimization (-Xms512m -Xmx1408m) with G1 garbage collection (GC) and explicit heap sizing on Managed Instances both contribute to tighter tail latency distribution. For services with SLAs on p99 response time, this reliability improvement matters more than median performance. For workloads with significant heap pressure, tuning -XX:MaxGCPauseMillis and monitoring GC logs can further tighten tail latency.

Why Lambda Managed Instances is faster: JIT compilation

The JVM’s Just-In-Time compiler works in tiers. The C1 compiler performs initial compilation quickly with basic optimizations. The C2 compiler profiles execution over hundreds of invocations and then applies aggressive optimizations: method inlining (eliminating function call overhead), escape analysis (allocating objects on the stack instead of the heap), loop unrolling (reducing branch overhead), and vectorization (processing multiple data elements in a single CPU instruction).

The following table presents JIT warmup progression using java.lang.management.

CompilationMXBean emitted through Amazon CloudWatch Embedded Metrics Format. We collected this data from a 1,500-request sustained load test on UC1 (PDF generation):

Phase Invocation Avg Latency What’s Happening
First requests (application init) 1 ~2,400ms JVM boot, spring context creation, SDK client setup
Early requests (C1 compiled) 2-100 ~145ms C1 compiler active. App is functional, but not optimized
Steady state (C2 optimized) 1000+ ~38ms C2 optimizations completed

The first invocation includes one-time application start costs: class loading, Spring context initialization, and DynamoDB client construction. These costs are unrelated to JIT compilation and occur on any deployment mode.

Once C1 compilation stabilizes during early invocations, latency reaches approximately 145ms. This is the baseline compiled performance. Over the next several hundred invocations, the C2 compiler profiles hot code paths and applies optimizations. By invocation 1,000, latency drops to 38ms. This represents a 3.8x improvement from JIT optimization alone.

Standard Lambda environments typically recycle before C2 completes its optimization passes. On Managed Instances, concurrent requests share the same JVM. This accelerates JIT profiling: three concurrent requests generate three times the method invocation data for the C2 compiler to optimize. The C2 compiler profiles execution patterns across all concurrent requests. It identifies hot code paths faster and applies optimizations sooner than single-concurrency environments.

What this means: CPU-bound workloads see the largest gains (30% faster median latency on UC1) because the JIT compiler has more opportunity to optimize tight loops and method calls. I/O-bound workloads see smaller gains (18% faster on UC3) because network latency to DynamoDB, SQS, and SNS dominates request duration. The JIT compiler still optimizes your code, but the network time remains constant across all deployment modes.

Choosing the right mode

No single mode wins in every scenario. The right choice depends on your traffic pattern, cold-start tolerance, team expertise, and operational complexity budget.

Lambda Managed Instances is ideal for steady-state traffic patterns above 5 requests per second with low cold-start tolerance (p99 SLA under 500 ms). Best for workloads with predictable, sustained traffic that need low latency with zero cold starts. Managed Instances excels at CPU-bound workloads where JIT optimization compounds.

SnapStart works well for variable traffic patterns where cold-start reduction matters. Choose this as the default for Java Lambda functions. SnapStart reduces cold starts with minimal code changes (add CRaC priming). You have no additional infrastructure to manage. Works with the existing Lambda scaling model.

GraalVM Native Image works well for bursty traffic patterns with strict cold-start tolerance (sub-second cold starts required). Ideal if your team can invest in AOT compatibility (reflection configuration, build pipeline). This mode offers a smaller memory footprint. Requires testing for SDK compatibility.

Standard Lambda is the baseline for low-traffic or burst workloads where cold starts of 6-14 seconds are acceptable. Works well when invocation frequency is low enough that per-request billing is cheaper than fixed instance costs, or when operational simplicity is the top priority.

For example, if you run a Spring Boot API handling 100 requests per second with a 400 ms p99 SLA, Lambda Managed Instances reduces your p99 from 353 ms (cutting it close) to 225 ms (comfortable margin) and removes the multi-second cold start spikes that violate your SLA entirely.

Dimension Standard SnapStart Native Managed Instances
Cold start 6-14 s 2-7 s 800 ms – 2 s None
Warm p50 (CPU-bound) 139 ms 127 ms 107 ms 97 ms
Tail latency Worst Better Good Fastest
Error rate Low Low Higher (SDK compat) Low
Operational complexity Lowest Low High (build pipeline) Medium (VPC, sizing)
Burst scaling Fastest Fastest Fastest Slower (capacity provider)
Migration effort None Low (add CRaC priming) High (AOT compat, reflection configuration) Medium (capacity provider, VPC, thread safety)
Memory efficiency Good Good

Lowest

(125-154 MB)

Fixed per instance

Lambda Managed Instances supports Graviton4 (arm64) instances, which offer approximately 20% better price-performance based on AWS published Graviton4 benchmarks. These benchmarks use x86_64 for consistency across all four modes (GraalVM native cross-compilation to arm64 adds complexity). The arm64 parallelization characteristics could shift the performance curves for longer-lived deployment modes like Managed Instances in ways worth exploring in a future post.

Cost considerations

Lambda Managed Instances uses instance-based pricing rather than per-invocation billing. For steady-state workloads above approximately 9 requests per second, the fixed instance cost is lower than equivalent Standard Lambda GB-second charges. You can use the official pricing calculator to compare Managed Instances and standard Lambda costs.

Try it with your runtime version

These benchmarks use Java 25 with Spring Boot 4.0.6. The GitHub repository also includes configurations for Java 21 with Spring Boot 3.x. The repository README walks you through deployment, load testing, and collecting your own metrics.

Conclusion

This post demonstrates how Lambda Managed Instances solves a fundamental Java-on-serverless mismatch. The JVM’s JIT compiler needs time to optimize hot code paths. Standard Lambda recycles environments before the JVM reaches peak optimization. Managed Instances keeps the JVM alive across invocations, allowing the C2 compiler to reach peak optimization. The benchmarks show the impact. In these benchmarks, Managed Instances delivered 18 to 30% faster p50 latency than Standard Lambda. Tail latency improved 27 to 41% at p99. Maximum response times dropped 3 to 30x on CPU-bound workloads. The 3.8x improvement from JIT optimization alone shows what’s possible when the runtime has time to complete its work.

For more information, refer to the Lambda Managed Instances documentation. The GitHub repository contains the complete benchmark code, SAM templates, and deployment instructions. Share your results in the comments and let the community know how Managed Instances performs on your workloads. To delete all benchmark resources and avoid ongoing charges, run the cleanup commands documented in the GitHub repository README.

Announcing Lambda MicroVMs: serverless compute environments with VM-level isolation and near-instant startup

Post Syndicated from Ayush Kulkarni original https://aws.amazon.com/blogs/compute/announcing-lambda-microvms-serverless-compute-environments-with-vm-level-isolation-and-near-instant-startup/

We recently announced the launch of AWS Lambda MicroVMs, a new serverless compute primitive that provides VM-level isolation, near-instant startup performance, and state retention. You can now give each user or job their own execution environment to securely run just-in-time code – either user or AI generated – without managing virtualization infrastructure or choosing between isolation, speed, and state retention. Lambda MicroVMs are powered by Firecracker virtualization, the technology underpinning AWS Lambda. You can use Lambda MicroVMs to build data analytics applications, AI sandboxes, vulnerability scanners, and interactive development environments.

Evolution of serverless compute

When we launched AWS Lambda in 2014, the premise was simple: give developers a way to run code without thinking about servers. Upload a handler, configure a trigger, and let the service handle infrastructure provisioning, scaling, patching, and availability. Over the past decade, Lambda has grown to process tens of trillions of requests each month for over 1.5 million customers. Under the hood, those invocations run inside a Lambda-managed Firecracker microVM – a lightweight virtual machine that combines hardware-level virtualization and near-instant startup speed. With Lambda SnapStart, we used Firecracker’s snapshotting capabilities to accelerate startup times by resuming execution environments from pre-initialized snapshots (carrying memory and disk state) rather than cold-booting them.

Today, a growing class of applications need to run code supplied by users or AI agents just-in-time – and need Firecracker’s core capabilities directly: hardware isolation, near-instant startup, and state retention over extended periods. Achieving this today often requires building custom infrastructure that diverts teams from core application development. We’ve been hearing this theme from customers across use cases and industry verticals:

  • Interactive code environments like browser-based IDEs, notebooks, and vibe-coding platforms need to deploy and execute user-generated code in per-user environments that start within seconds and retain state – like installed packages, generated files, and running processes – across interactions.
  • Data analytics platforms run user-supplied or LLM-generated queries and notebooks in isolated environments that retain large working sets over long durations – such as an 8-hour workday – with the ability to resume quickly after periods of inactivity.
  • AI coding assistants and agents run LLM-generated code iteratively, while retaining context between iterations, and rapidly launching and shutting down environments to evaluate alternative code paths, such as for reinforcement learning.
  • IT security scanners execute vulnerability assessments in compute environments that are strongly isolated from one another, can scale to handle bursts of concurrent scan requests, and support elevated operating system privileges.
  • CI/CD platforms need ephemeral, isolated build and test environments that start quickly and can be discarded after each run.

Introducing Lambda MicroVMs

Now, with AWS Lambda MicroVMs, developers can directly use the isolation, speed, and state snapshotting of Firecracker MicroVM as a primitive, while keeping the serverless simplicity of AWS Lambda. Lambda MicroVMs provide these key capabilities.

  1. Snapshot-based, near-instant startup: To optimize startup speed, MicroVMs are launched from MicroVM images, which are pre-initialized Firecracker snapshots of your application’s memory and disk state. When you create a MicroVM image, the service executes your Dockerfile, initializes your application, and snapshots the MicroVM. Lambda starts MicroVMs from this snapshot with your dependencies loaded.
  2. Direct HTTPS connectivity: Each MicroVM exposes a dedicated HTTPS endpoint for inbound connectivity to individual ports. You can connect to applications running within your MicroVM using standard HTTPS clients, WebSocket connections, or gRPC – exactly as you would with a container or VM.
  3. Lifecycle control with state retention: Lambda MicroVMs allow you to control the lifecycle of each execution environment, enabling you to support interactions that last a few minutes to sessions that span 8 hours.
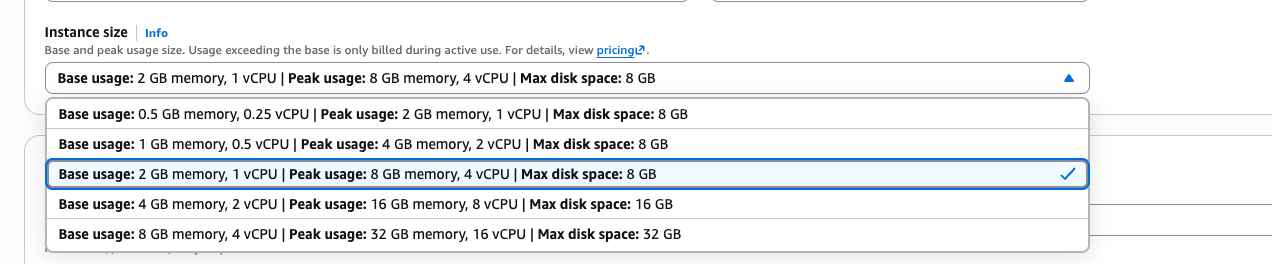
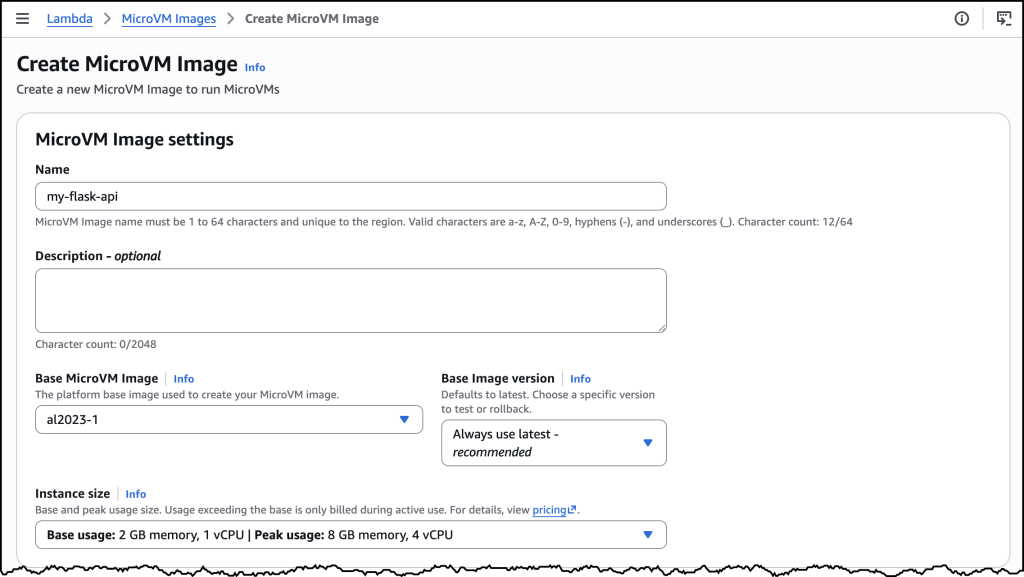
  4. Vertical and horizontal scaling: Each MicroVM starts with a configurable baseline — 2 GB memory and 1 vCPU by default (up to 8 GB and 4 vCPUs), with CPU allocated in a 2:1 ratio to memory. From that baseline, MicroVMs scale vertically by up to 4x automatically, meeting peak resource demands for each user or session without any action on your part. MicroVMs also scale horizontally — you can launch several hundred within a minute during traffic spikes. For details on service limits, refer to Lambda service quotas.
  5. Internet and VPC access: By default, Lambda MicroVMs support outbound connectivity to the public internet without additional configuration. For private VPC connectivity to resources such as databases or internal APIs, you can use a Lambda Network Connector (LNC). LNC is a new Lambda resource that provides managed, configurable network connectivity between your MicroVMs and your private VPC.

Building with Lambda MicroVMs

Lambda MicroVMs introduces two core resource types: a MicroVM image – a versioned artifact containing your runtime environment and application code, and MicroVMs – individual instances launched on demand from a MicroVM image.

Let’s make this concrete with an example. You are a cloud architect building a data analytics application which under the hood, manages compute environments to generate insights for data analysts within your organization. Analysts load multi-gigabyte datasets and generate visualizations in sessions that last hours with idle gaps when they switch to other tasks. When analysts return, they expect to pick up exactly where they left off. Here’s how you can use MicroVMs for this workload:

Step 1: Define your environment

Write a Dockerfile that installs your data science stack. This runs once at MicroVM image build time – every analyst’s MicroVM starts with these dependencies already loaded. This Dockerfile builds a notebook server that accepts code execution requests, runs them in-process (so state accumulates across requests), and returns results. Your customer-facing UI calls this notebook server for each analyst.

FROM public.ecr.aws/lambda/microvms:al2023-minimal

# Install Python 3.12 and pip
RUN dnf install -y python3.12 python3.12-pip && dnf clean all

RUN pip3.12 install --no-cache-dir \
    pandas numpy scipy scikit-learn matplotlib seaborn \
    fastapi uvicorn boto3 pyarrow

COPY notebook_server.py /app/notebook_server.py
WORKDIR /app
EXPOSE 8080

CMD ["python3.12", "notebook_server.py"]

Next, package and upload your application artifacts and Dockerfile to S3.

zip -r notebook-env.zip Dockerfile notebook_server.py
aws s3 cp notebook-env.zip s3://amzn-s3-demo-analytics-platform/artifacts/notebook-env.zip --region us-east-1

With these in place, create a MicroVM image:

aws lambda-microvms create-microvm-image \
    --name analytics-notebook \
    --code-artifact '{"uri": "s3://amzn-s3-demo-analytics-platform/artifacts/notebook-env.zip"}' \
    --base-image-arn arn:aws:lambda:us-east-1:aws:microvm-image:al2023-1 \
    --build-role-arn arn:aws:iam::123456789012:role/NotebookBuildRole \
    --resources '[{"minimumMemoryInMiB": 4096}]' \
    --region us-east-1

When you create a MicroVM image, Lambda executes your Dockerfile, starts your application, and takes a Firecracker snapshot of the fully initialized environment with the libraries imported, and notebook server listening. Every MicroVM launched from this image skips this initialization step, and provides near-instant startup.

Step 2: Launch a MicroVM when an analyst starts their session

Once your MicroVM image is ready, you can start a new MicroVM for each analyst session. The idle policy encodes your business logic: auto-suspend after 5 minutes of inactivity, retain the suspended state for up to 8 hours (covers a full workday), and auto-resume when the analyst’s next request arrives. Within seconds, the analyst has a dedicated environment with their own filesystem, and a dedicated HTTPS endpoint.

aws lambda-microvms run-microvm \
    --image-identifier arn:aws:lambda:us-east-1:123456789012:microvm-image:analytics-notebook \
    --image-version 1.0 \
    --idle-policy '{"maxIdleDurationSeconds":300,"suspendedDurationSeconds":28800,"autoResumeEnabled":true}' \
    --maximum-duration-in-seconds 28800 \
    --execution-role-arn arn:aws:iam::123456789012:role/notebook-exec-role \
    --region us-east-1

# MicroVM endpoint url is returned by the run-microvm API call
ENDPOINT="https://a1b2c3d4-e5f6-7890-abcd-1234567890ef.lambda-microvm.us-east-1.on.aws"

When a data analyst submits a query, it is submitted as an HTTPS request to their assigned MicroVM. You can test this using curl on the MicroVM endpoint.

curl -X POST "$ENDPOINT/execute" \
    -H "X-aws-proxy-auth: $TOKEN" \
    -H "Content-Type: application/json" \
    -d '{"code": "import pandas as pd; df = pd.read_parquet(\"s3://amzn-s3-demo-data-lake/transactions.parquet\"); print(f\"Loaded {len(df)} rows, {df.memory_usage(deep=True).sum()/1e9:.1f} GB\")"}'

Notice that you can separate the build-time IAM role from the execution-time IAM role for finer-grained control over each tenant’s permissions.

Step 3: Suspend and resume during idle periods

After 5 minutes of inactivity, the MicroVM is automatically suspended based on the configured idle policy. When the MicroVM is suspended, its memory and disk state is preserved.

Two hours later, the analyst returns and sends the next query. The MicroVM auto-resumes within seconds. The memory and disk state are restored exactly as the analyst left them – no re-computation or re-loading required.

Analysts can also suspend and resume their MicroVMs directly using the APIs.

aws lambda-microvms suspend-microvm \
    --microvm-identifier microvm-a1b2c3d4-e5f6-7890-abcd-1234567890ef \
    --region us-east-1

aws lambda-microvms resume-microvm \
    --microvm-identifier microvm-a1b2c3d4-e5f6-7890-abcd-1234567890ef \
    --region us-east-1

Step 4: Connect to private data sources

If your data lives in a private VPC, for example, Amazon Redshift clusters or RDS databases, you can use a Lambda Network Connector (LNC) to give your analysts MicroVMs access to this data. Create a network connector once:

aws lambda-core create-network-connector \
    --name analytics-vpc \
    --configuration '{"VpcEgressConfiguration":{"SubnetIds":["subnet-data1","subnet-data2"],"SecurityGroupIds":["sg-analytics"],"NetworkProtocol":"IPv4","AssociatedComputeResourceTypes":["MicroVm"]}}' \
    --operator-role arn:aws:iam::123456789012:role/ConnectorRole \
    --region us-east-1

Then, reference it when starting a MicroVM. Re-use network connectors across all MicroVMs that share the same network configuration.

aws lambda-microvms run-microvm \
    --image-identifier arn:aws:lambda:us-east-1:123456789012:microvm-image:analytics-notebook \
    --egress-network-connectors '["arn:aws:lambda:us-east-1:123456789012:network-connector:analytics-vpc"]' \
    --idle-policy '{"maxIdleDurationSeconds":300,"suspendedDurationSeconds":28800,"autoResumeEnabled":true}' \
    --region us-east-1

Now, your organization’s analysts can query private databases directly from their notebook environment.

Step 5: Cleaning up

To stop incurring charges, terminate any running MicroVMs and delete unused resources.

# Terminate the MicroVM
aws lambda-microvms terminate-microvm \
    --microvm-identifier microvm-a1b2c3d4-e5f6-7890-abcd-1234567890ef \
    --region us-east-1

# Delete the network connector (if created)
aws lambda-core delete-network-connector \
    --identifier analytics-vpc \
    --region us-east-1

# Delete the MicroVM image
aws lambda-microvms delete-microvm-image \
    --image-identifier arn:aws:lambda:us-east-1:123456789012:microvm-image:analytics-notebook \
    --region us-east-1

To recap, with MicroVMs we build an image once, launch isolated MicroVMs per user or job, interact over HTTPS, suspend when idle, and terminate when done. This pattern applies broadly, across use cases. For instance, an IT security platform scanning customer repositories has similar requirements: an isolated environment per scan, the ability to run with elevated operating system privileges, and rapid horizontal scaling to hundreds of concurrent scans. Similarly, an AI coding assistant needs per-developer sandboxes that retain installed packages and generated files across iterative code-write-test cycles, with suspend/resume preserving context when developers switch tasks. In each case, the workflow is the same.

Building MicroVMs with Agent Toolkit for AWS

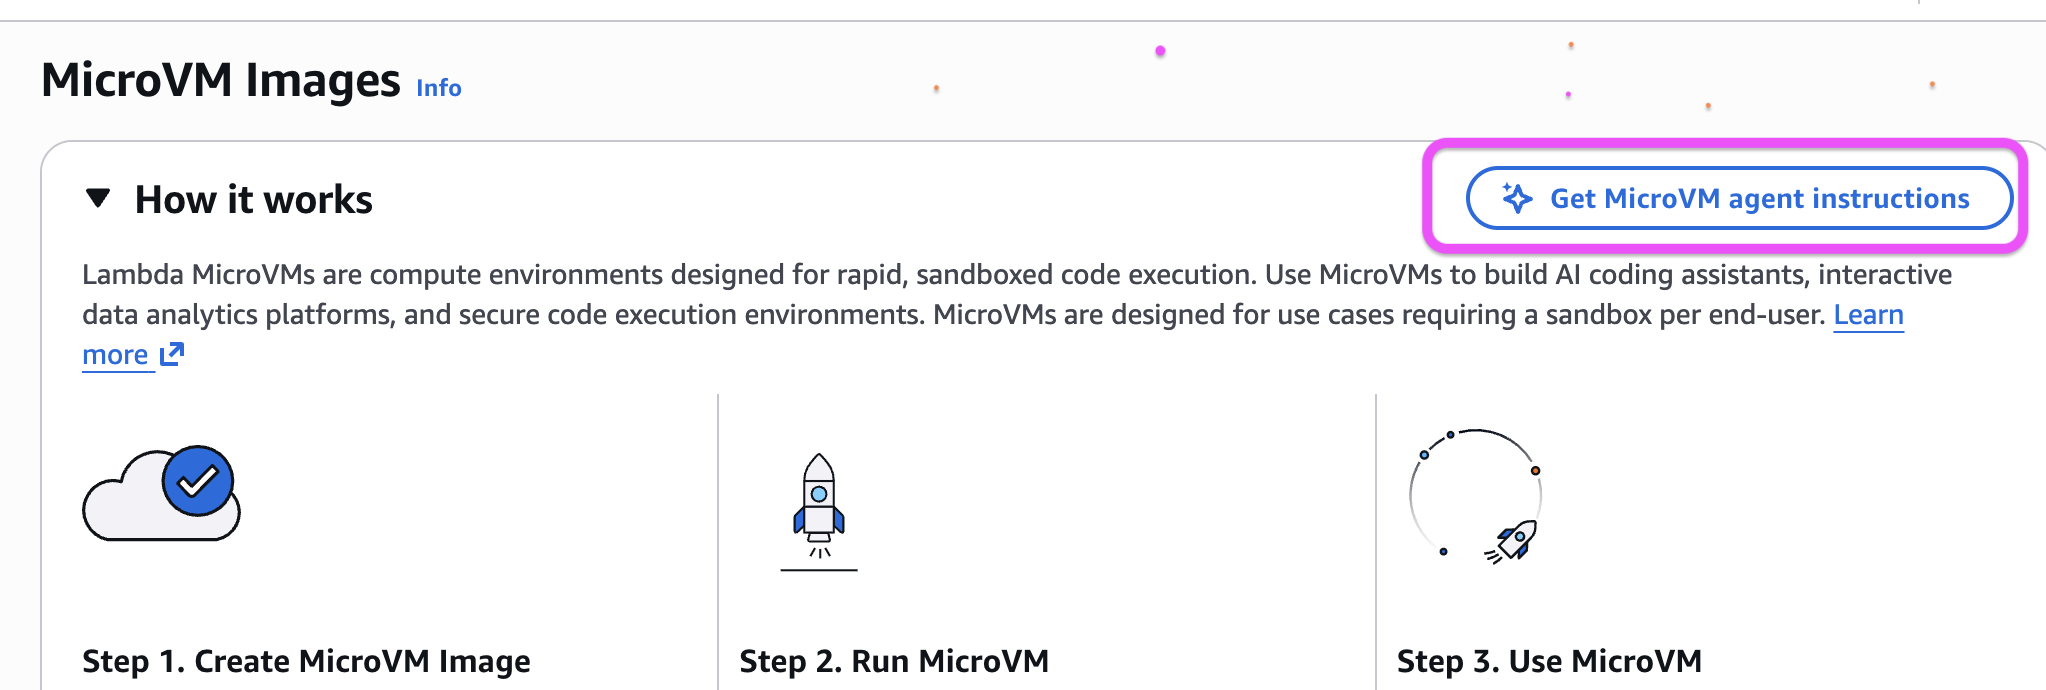
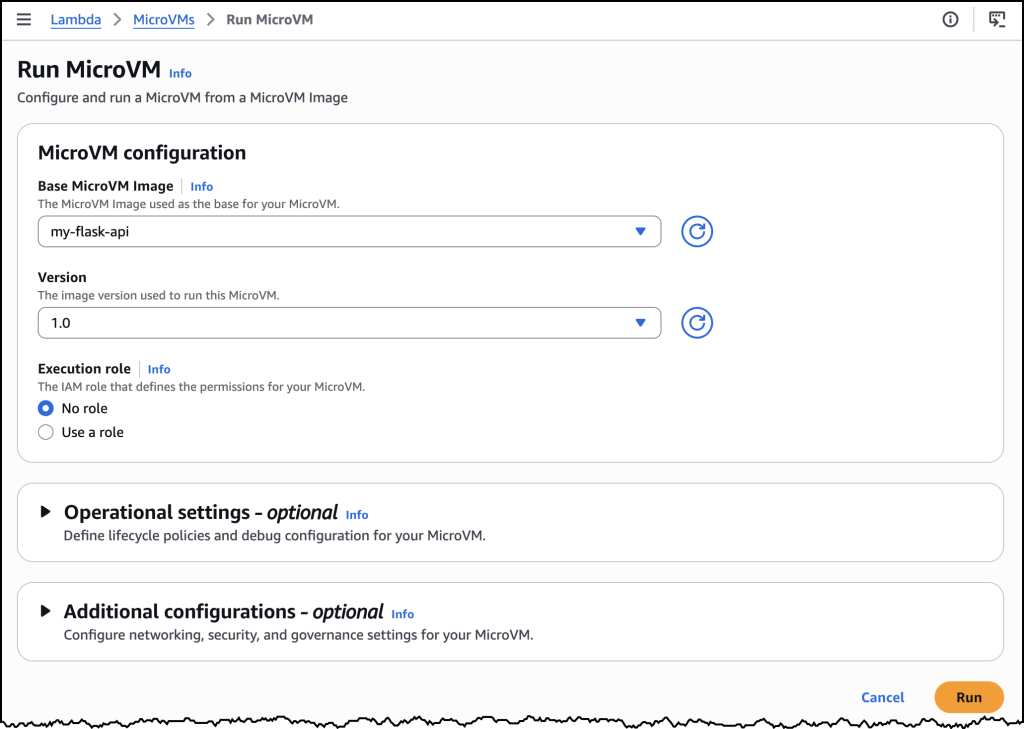
In the previous section, we demonstrated Lambda MicroVMs core API operations. You can also use your preferred Agentic development tools to start developing with Lambda MicroVMs. Simply install the AWS Lambda MicroVMs skill from the Lambda MicroVMs console, or use the Agent Toolkit for AWS.

To get started in the AWS Lambda console, choose the highlighted button to access the MicroVMs agent instructions as in Figure 1:

Figure 1: Access MicroVM agent instructions

Figure 1: Access MicroVM agent instructions

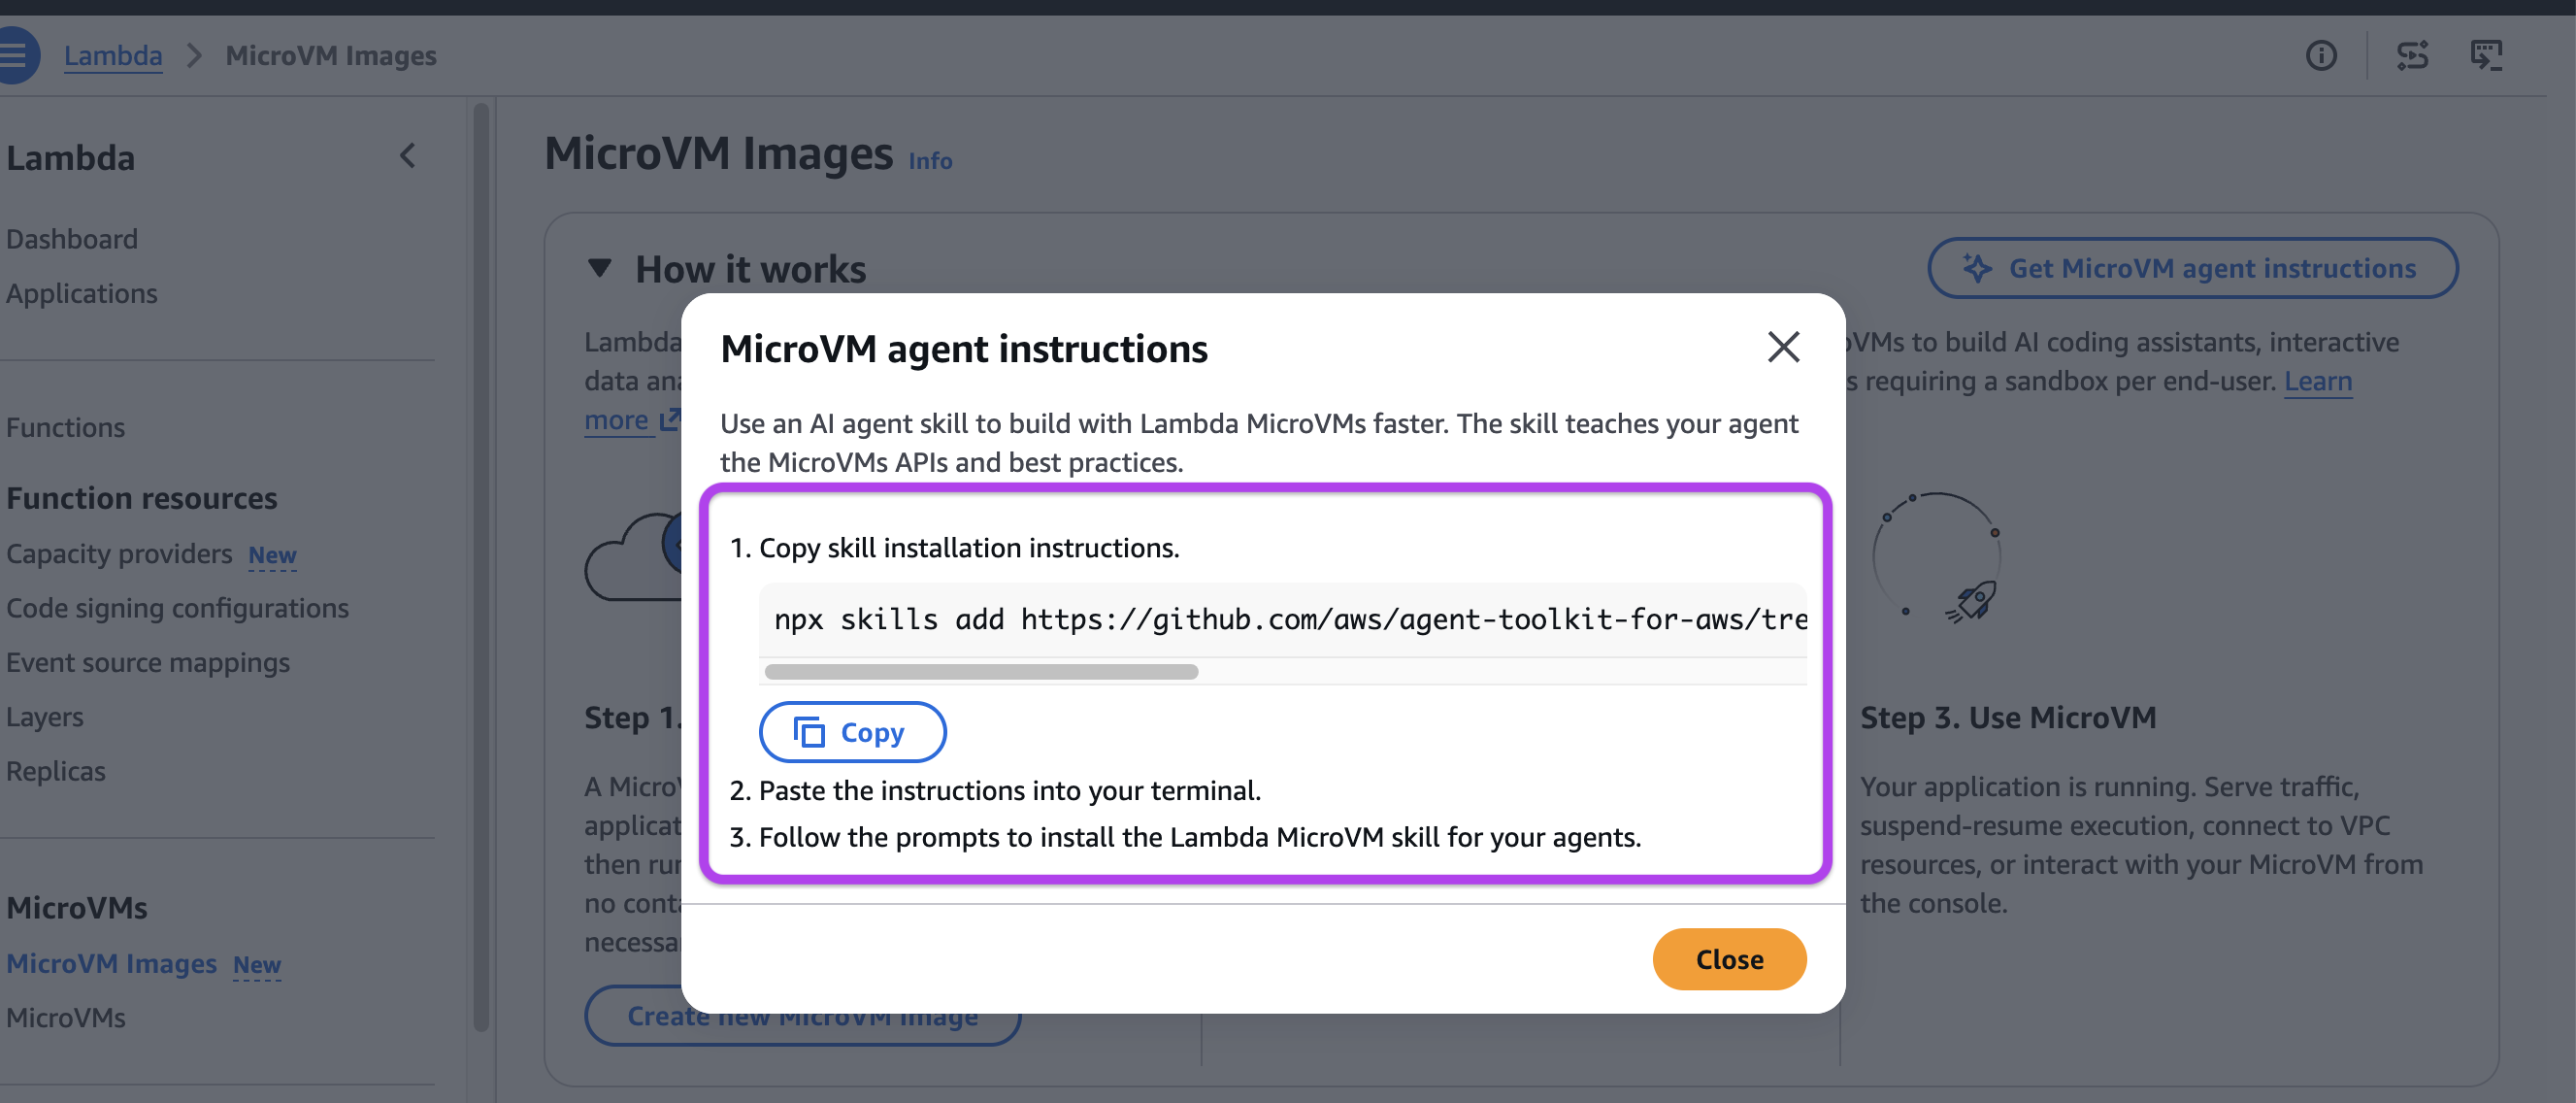
Next, copy the agent installation instructions and paste it in your terminal to begin developing.

Figure 2: Copy agent instructions

Figure 2: Copy agent instructions

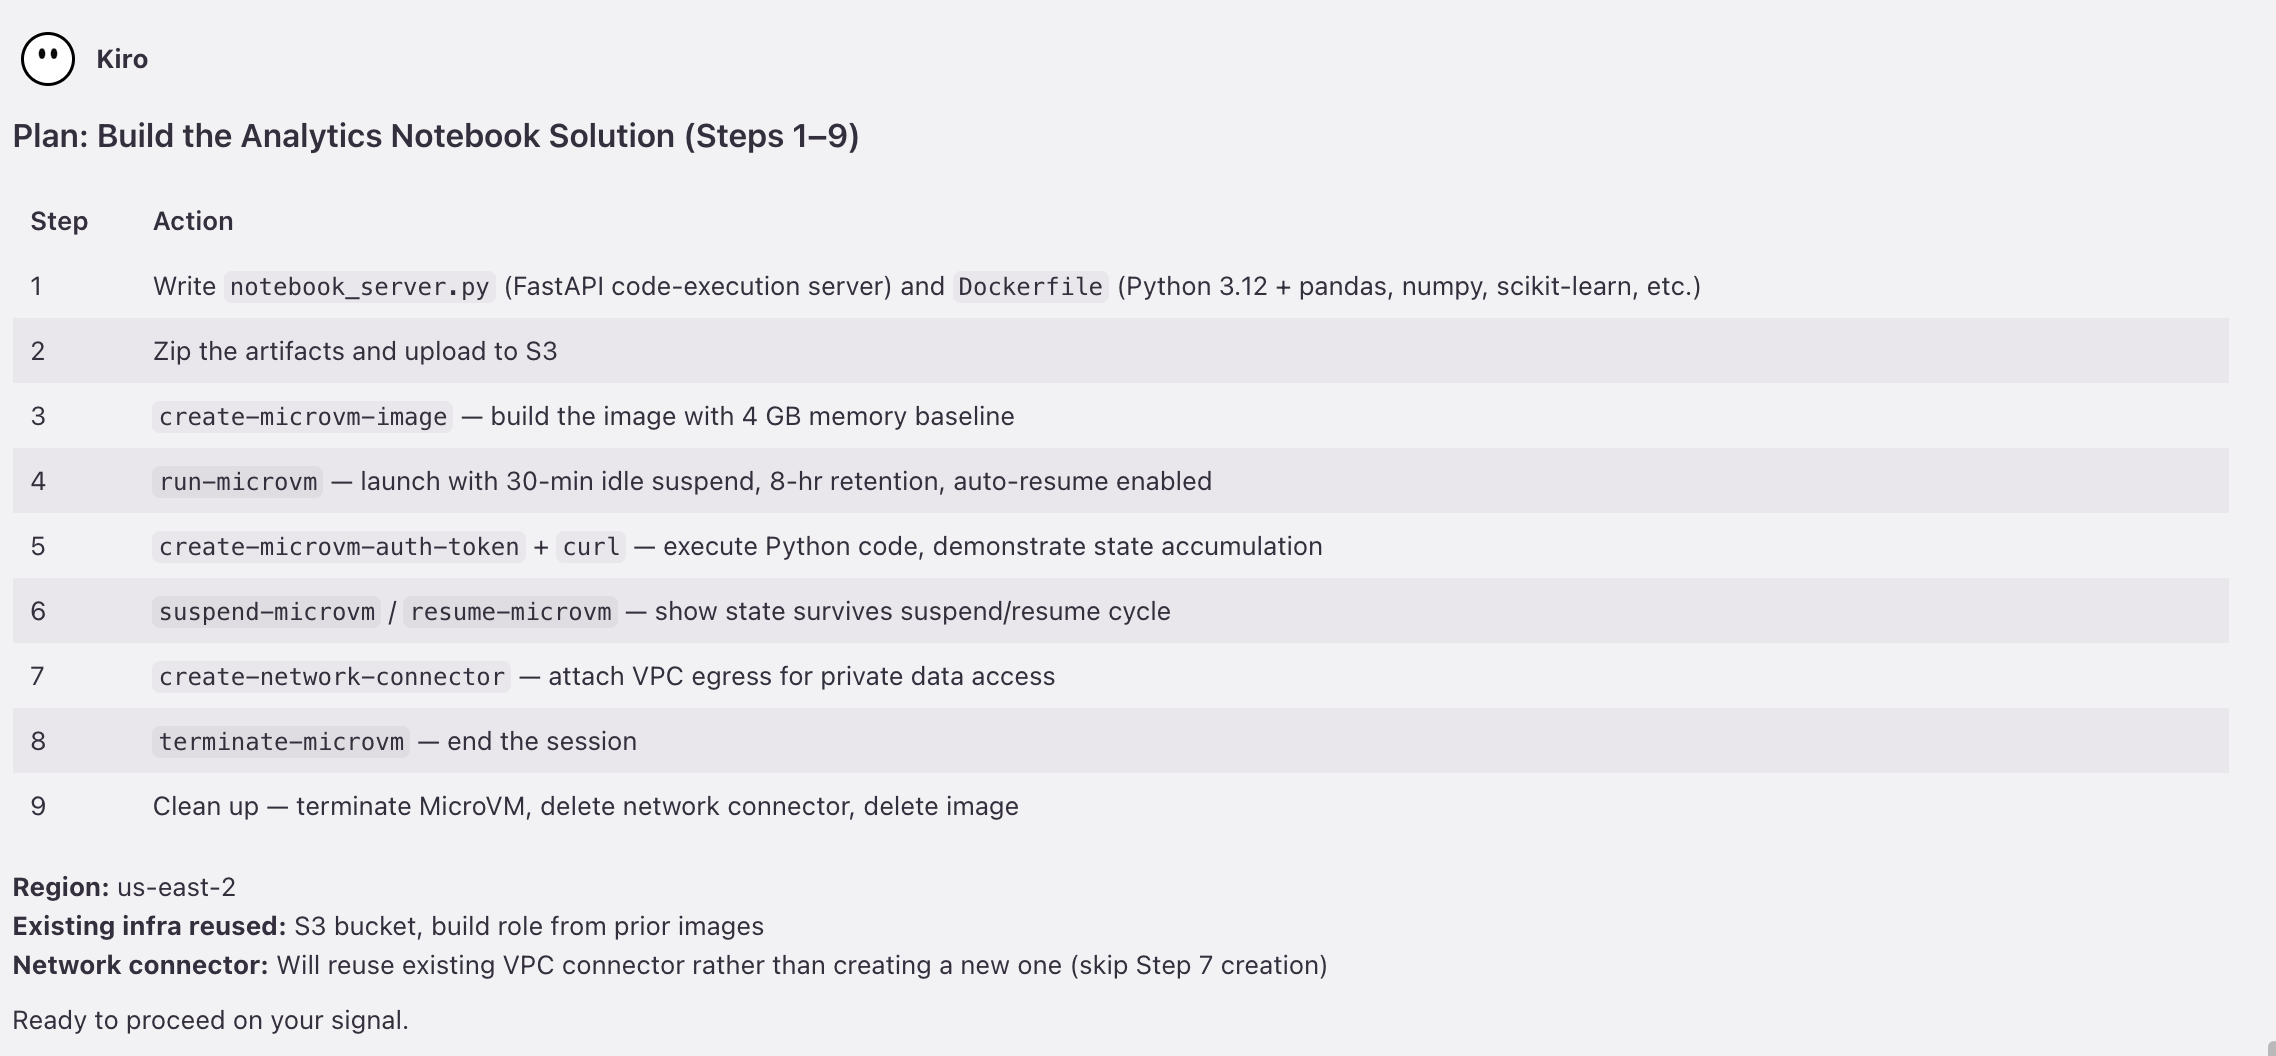
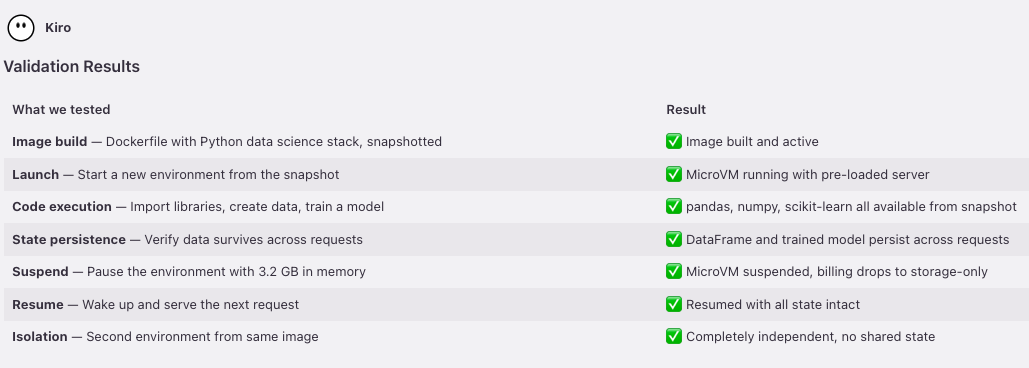
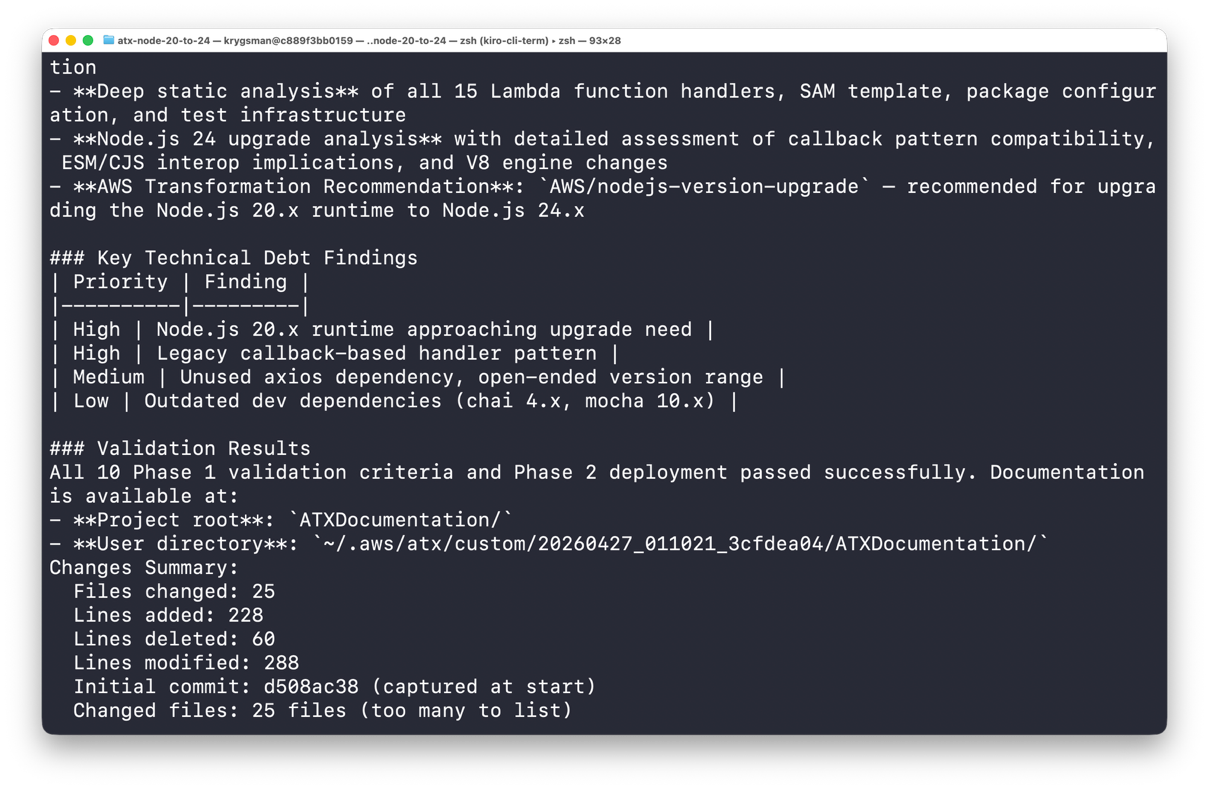
The following screenshot demonstrates the skill in action in an AI coding assistant. Using the skill, the coding assistant agent generates a detailed plan to build the analytics notebook solution, executes the plan, and validates correct execution.

Figure 3: Agent-driven development with MicroVMs

Figure 3 continued: Agent-driven development with MicroVMs

Figure 3 continued: Agent-driven development with MicroVMs

Lambda MicroVMs as sandboxes for Claude Managed Agents

You can also use AWS Lambda MicroVMs as a managed sandbox provider for Claude Managed Agents self-hosted sandboxes. This pattern keeps the orchestration within your Anthropic environment, which hosts the agent loop and Claude model, but moves tool execution into AWS Lambda MicroVMs, so the agent’s code, filesystem, and network egress never leave the infrastructure you control. You control the execution environment – what is installed, what network access is available, and what resources the agent can reach. For integration details, refer to the Lambda MicroVMs developer guide.

Snapshot compatibility considerations

Lambda MicroVMs are started from snapshots of pre-initialized memory and disk state. This has a few implications for how you build applications:

Uniqueness: Content generated and retained within a MicroVM image is shared across all MicroVMs started from that image. To maintain uniqueness for content such as unique IDs, secrets, or random seeds, generate these values after each MicroVM is started. If your application code uses OpenSSL, use the AWS-provided base container image from public.ecr.aws/lambda/microvms:al2023-minimal to build your MicroVM image.

Ephemeral credentials and network connections: Credentials and connections established during MicroVM image creation – or before a MicroVM is suspended – may expire or terminate by the time the MicroVM starts or resumes. Design your application to refresh these credentials and re-establish connections on startup. AWS SDK clients re-establish connections automatically in most cases.

Lambda MicroVMs provides lifecycle hooks that are executed when a MicroVM is started or resumed. Use these hooks to restore uniqueness and to re-establish network connections or ephemeral credentials. For more details, refer to the Working with snapshots section in the Lambda MicroVMs developer guide.

Pricing

Lambda MicroVMs pricing comprises compute, snapshots, and data transfer (at standard AWS rates, including data transferred to your VPC). You have two cost management levers: baseline-plus-consumption billing and idle-suspension. With baseline-plus-consumption billing, your bill tracks closer to your actual resource usage rather than peak resource usage. You configure your MicroVM’s baseline resource allocation to match your workload’s average resource utilization – not peak. During peak activity, your MicroVM can vertically scale up to 4x of the configured baseline automatically and resource usage above the baseline is only billed during active use. You configure the baseline by setting memory, and CPU is allocated in a 2:1 memory-to-CPU ratio – the default is 2GB / 1vCPU, with a corresponding peak of 8 GB / 4 vCPU. Supported baseline and peak values are shown in Figure 4.

Figure 4: Baseline and peak resource configuration

Figure 4: Baseline and peak resource configuration

During extended idle periods, you can suspend your MicroVM to preserve memory and disk state at storage-only rates, resuming near-instantly when needed – no compute charges while suspended. For full pricing details, see AWS Lambda pricing.

Conclusion

Lambda MicroVMs extends the serverless compute model beyond invocation-based functions to long-running, stateful environments that execute code supplied by end users or AI. Development teams can focus on core application development while Lambda provides secure isolation and near-instant startup performance. Whether you’re building an AI coding assistant, an interactive development platform, an IT security platform, or a data analytics workload, the pattern is the same: define your environment in a Dockerfile, build a MicroVM Image once, launch isolated MicroVMs on demand, interact over HTTPS, and terminate when done.

To get started, visit the AWS Lambda MicroVMs developer guide or start building with the MicroVMs agent skill, available through the AWS Lambda console.

Secure code execution for AI agents with AWS Lambda MicroVMs

Post Syndicated from Shridhar Pandey original https://aws.amazon.com/blogs/compute/__trashed-4/

Development teams building serverless applications with AI coding agents face the question of how to let those agents generate and execute code without losing control over governance. Agent-generated code needs a secure environment to execute, isolated from production systems and the developer’s local environment. Addressing this requires three things working together: a secure execution sandbox, domain expertise to build correctly, and governance over what agents are allowed to do. This post shows how you can use AWS Lambda MicroVMs, the Agent Toolkit for AWS, and Policy in Amazon Bedrock AgentCore to let AI coding agents build, test, and deploy serverless applications safely with granular governance controls.

Overview

AI coding agents like Claude Code, Kiro, and Cursor accelerate serverless development by generating code, installing dependencies, running tests, and deploying infrastructure on behalf of developers. But today, most of that work executes with whatever permissions and access the developer has. If the agent acts outside its intended scope, whether by mistake or through prompt manipulation, there is no boundary between the agent’s actions and the rest of the environment.

Moving from proof-of-concept (PoC) to production requires isolating agent-generated code into a contained environment where it can execute freely without affecting the host environment or other tenants. It requires embedded domain expertise so agents produce production-grade output rather than improvising from general training data. And it requires deterministic governance that controls what agents are allowed to do regardless of how they are prompted.

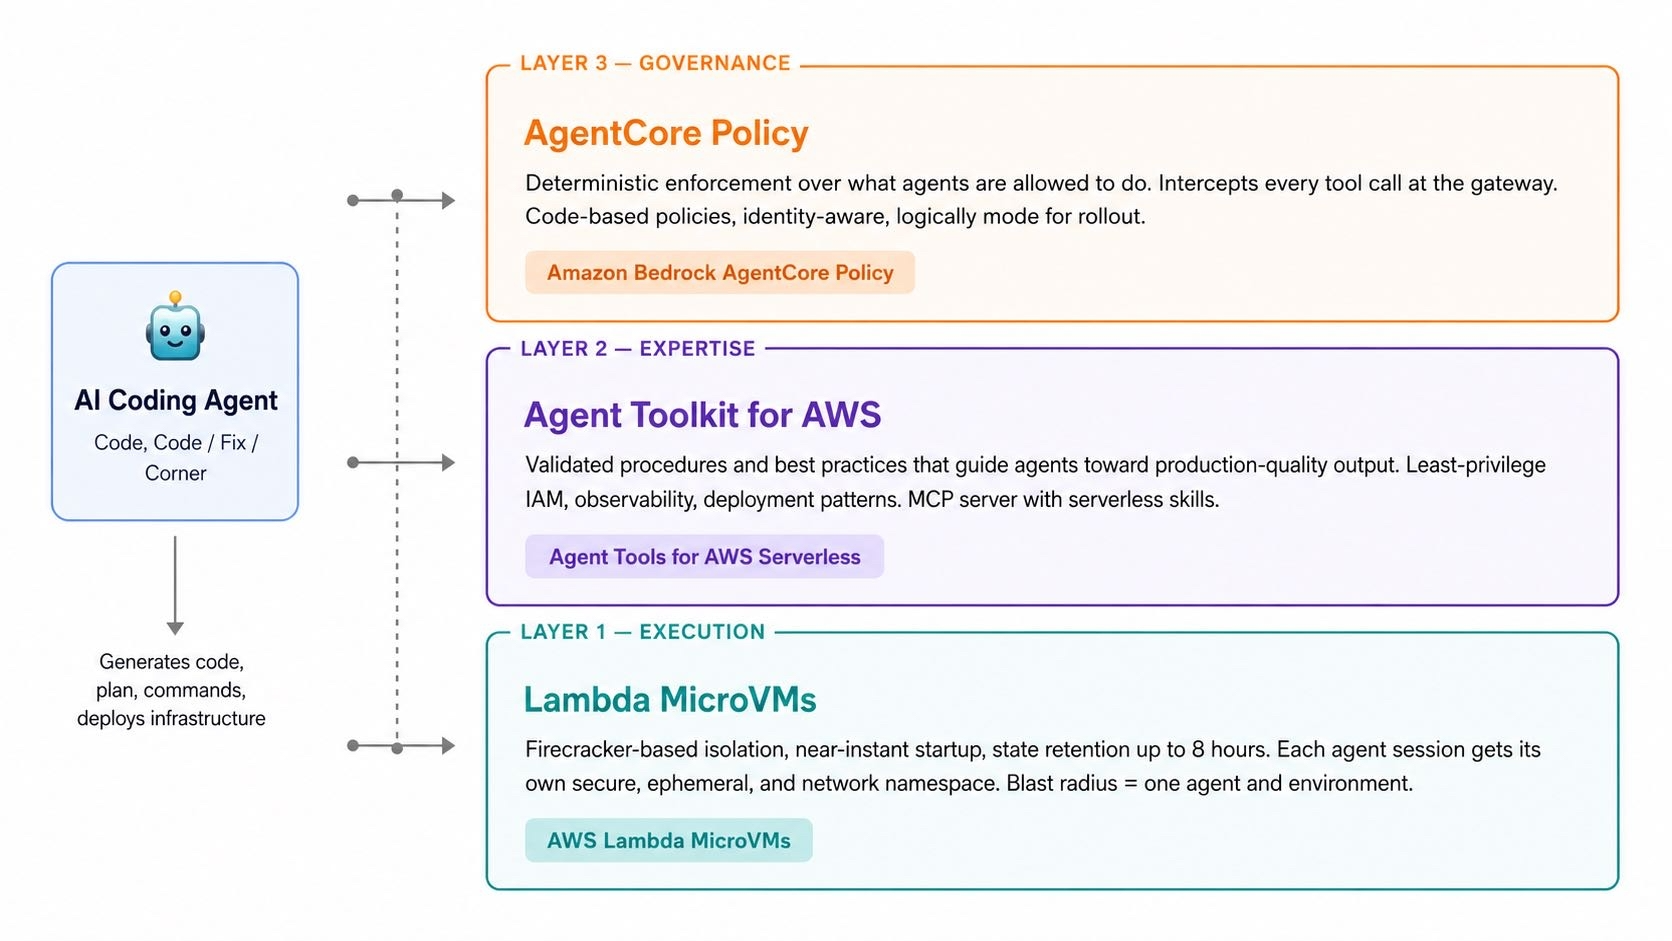
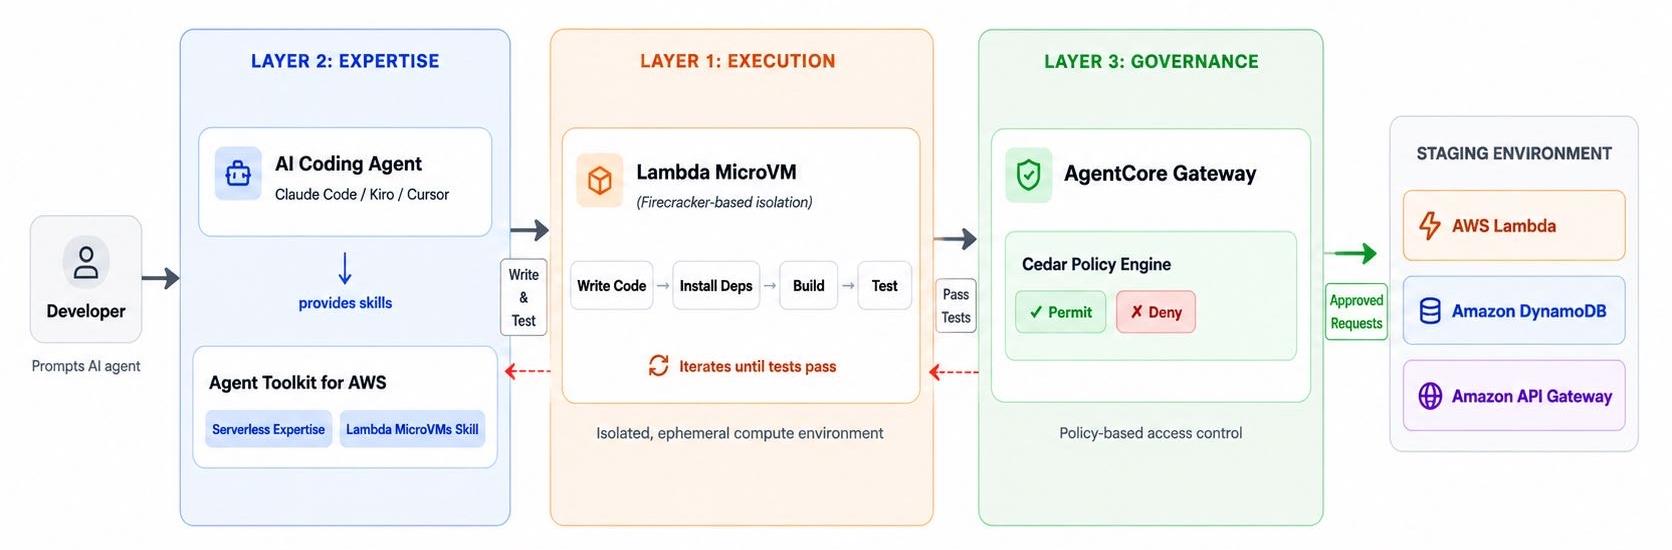
Each of these requirements maps to a specific layer in the stack. Lambda MicroVMs provide an isolated, ephemeral compute environment where agents write, build, test, and run code. The Agent Toolkit for AWS provides validated procedures and best practices that guide agents toward production-quality output. Policy in AgentCore enforces deterministic authorization over agent-to-tool interactions at the boundary.

Each layer solves a problem the other two cannot. Without expertise embedded in the workflow, agents running in isolation still produce code that fails in production. Without governance, even well-guided agents can overstep their boundaries. And without execution isolation, governance policies can be circumvented at the runtime level. The three layers work as a unit.

Figure 1 Three-layer stack for secure code execution for AI agents

Figure 1 Three-layer stack for secure code execution for AI agents

Layer 1: Execution (Lambda MicroVMs)

Code generated by AI agents needs a secure environment to execute, isolated from production systems, other tenants, and the host environment. Lambda MicroVMs provide a Firecracker-based compute environment with its own kernel, its own filesystem, and its own network namespace. This is the same isolation foundation that has powered Lambda since 2018, now available as a standalone compute substrate. Inside a MicroVM, agents can perform the same operations a developer would on their local machine, such as installing packages, running shell commands, executing build toolchains, and running tests. The difference lies in containment. If the agent generates destructive code, whether through hallucination or prompt injection, the impact is limited to a single ephemeral environment.

Each MicroVM provides operating system access with configurable vCPU, memory, and disk. Agents can run user sessions for up to 8 hours, with configurable network access (public or virtual private cloud (VPC)-only). MicroVMs can be suspended and resumed with their state preserved, giving agents state retention across sessions without sacrificing isolation between tenants.

Layer 2: Expertise (Agent Toolkit for AWS)

Execution isolation alone is not enough. An agent that runs in a MicroVM but improvises from general training data is unlikely to produce production-grade output. For example, it might generate Lambda functions with overly broad IAM permissions, skip observability configuration, or deploy without safe rollback patterns. The Agent Toolkit for AWS gives coding agents validated, up-to-date procedures for AWS tasks. Instead of improvising, agents using the Agent Toolkit follow curated skills that encode how an experienced engineer actually builds on serverless. The toolkit encodes least-privilege IAM by default, observability wired in from the start, and deployment patterns that reflect production best practices.

For Claude Code and Cursor, the Agent Plugin for AWS Serverless packages these skills as a plugin. In Kiro and other tools that support agent skills, they are available directly. These skills dynamically load relevant guidance throughout the development lifecycle, from project initialization through deployment and troubleshooting. This includes a dedicated Lambda MicroVMs skill that gives agents the procedures to provision, configure, and use MicroVM environments directly.

Layer 3: Governance (Policy in AgentCore)

Expertise without governance can produce correct code with no boundaries on what actions the agent can perform. For example, an agent following best practices can still deploy to production, overwrite existing infrastructure, or access data outside its scope. Policy in AgentCore intercepts every tool call at the Amazon Bedrock AgentCore Gateway and evaluates it against Cedar policies before allowing execution. Cedar is an open-source authorization language purpose-built for fine-grained permissions. Its policies are human-readable, analyzable by machines, and evaluate deterministically regardless of how the agent was prompted. The gateway exposes the available tools to the agent. Cedar can inspect tool input parameters, the identity of the user the agent is acting on behalf of, and the specific tool being invoked. A policy can permit an agent to call a deploy tool but deny it when the environment parameter is production.

The enforcement operates entirely outside the agent’s reasoning loop, so policy decisions are not influenced by the model’s context or prompt. Actions that would always be denied are omitted from the agent’s tool list entirely, so the agent never even attempts them. A log-only mode supports incremental rollout, and every enforcement decision is logged to Amazon CloudWatch for audit.

The agentic serverless stack in action

The following walkthrough shows an AI coding agent building and deploying an order processing API using the three layers working together. The same approach applies to any serverless workload, whether it is an event pipeline, a data transform, or a webhook handler. The developer prompts the agent to build the API. The agent uses the Lambda MicroVMs skill to provision its execution environment, then works autonomously within it. It follows Agent Toolkit skills for production best practices, and invokes deployment tools through the AgentCore Gateway under a Cedar policy that controls what it is allowed to do.

Figure 2 End-to-end workflow from developer prompt to governed deployment

Figure 2 End-to-end workflow from developer prompt to governed deployment

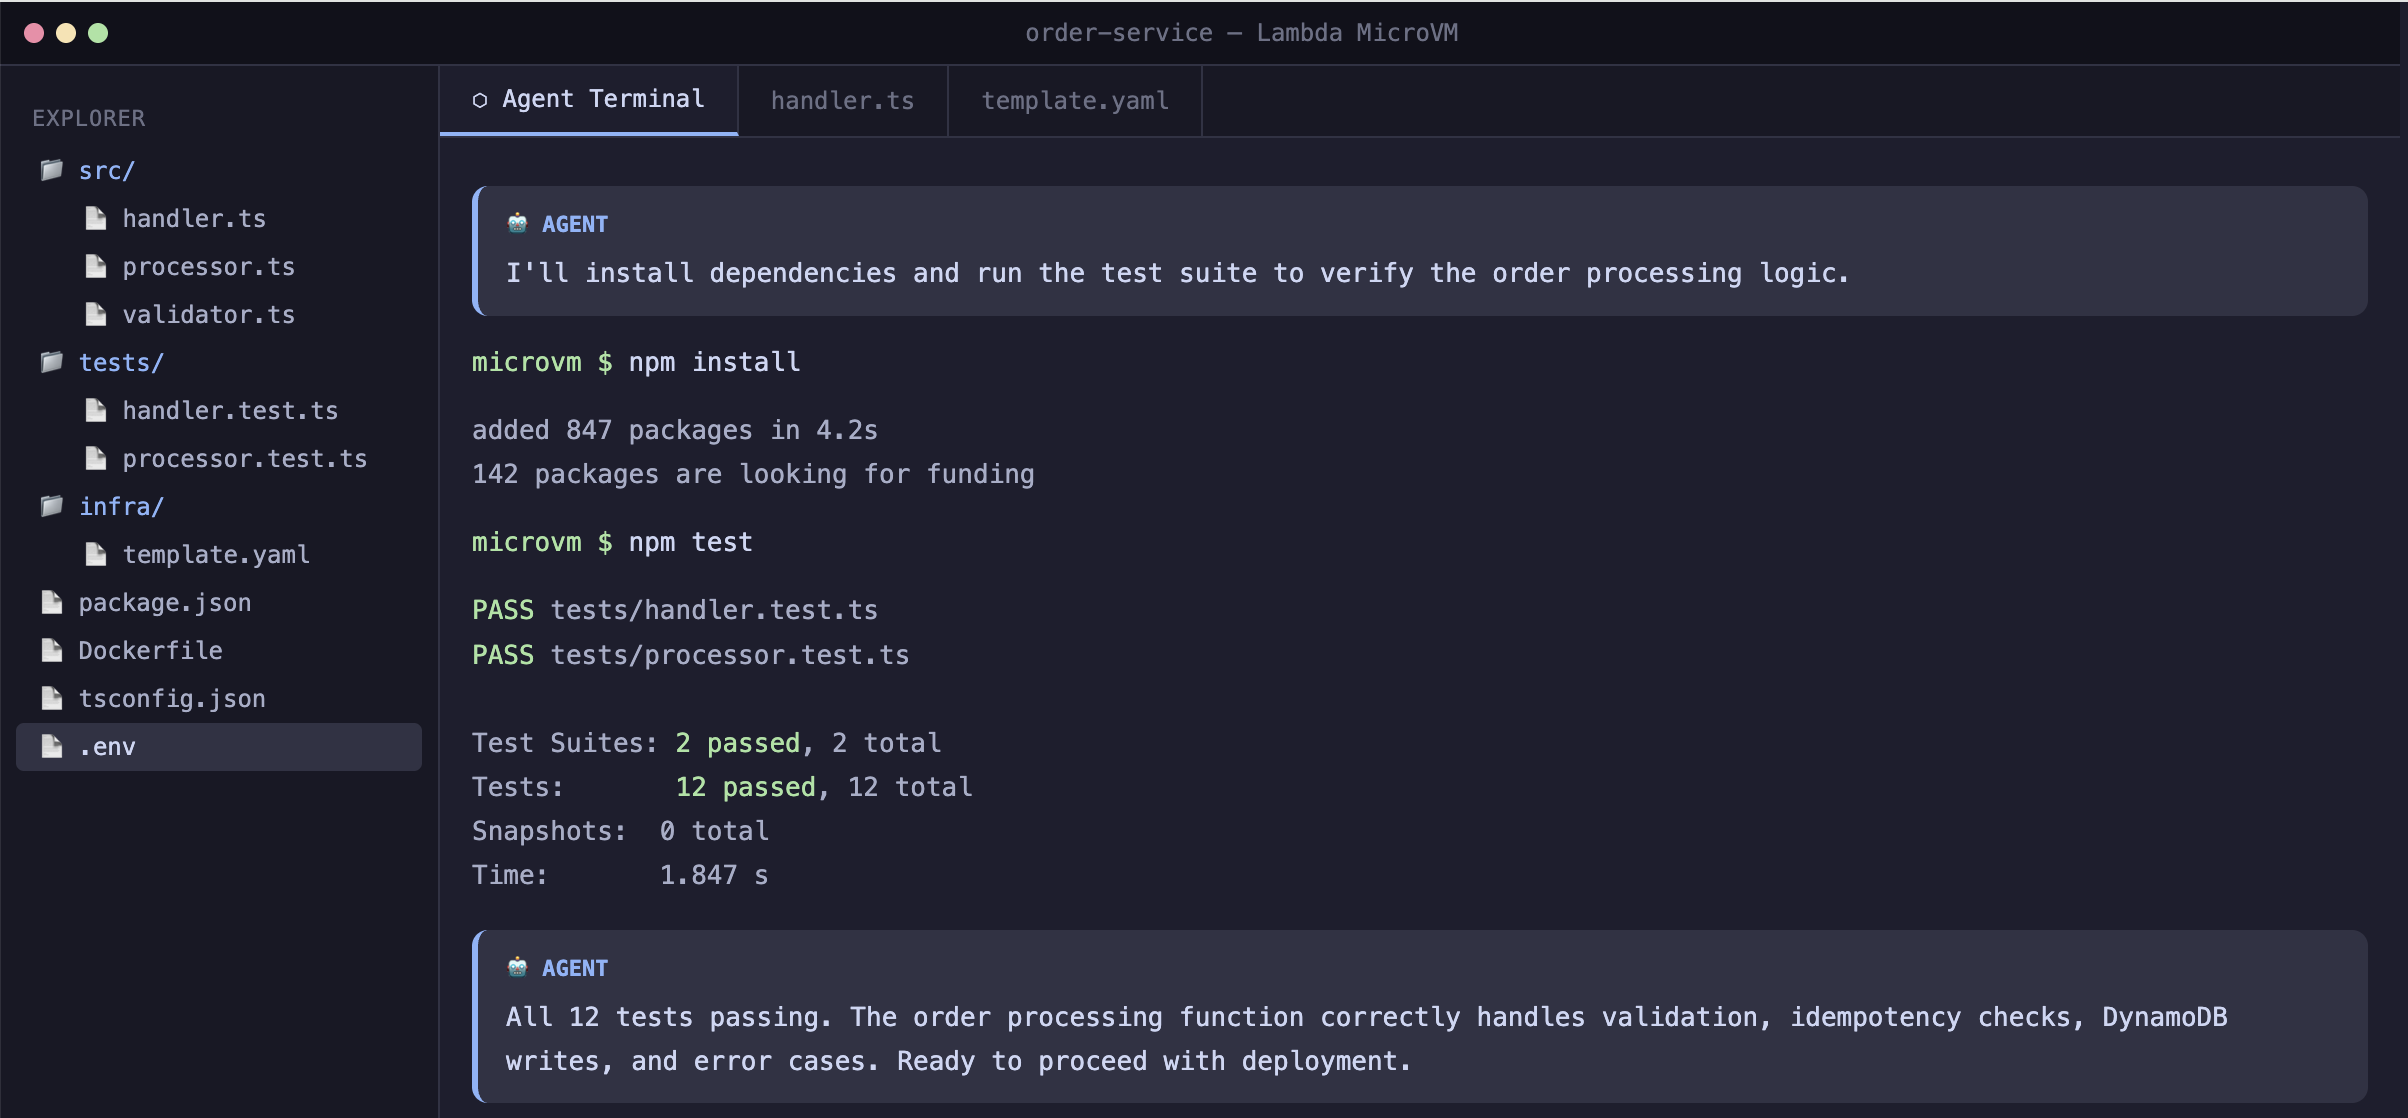
Step 1: Write and test inside the MicroVM. The agent starts inside a MicroVM. It scaffolds the application, installs dependencies, and runs the test suite until all tests pass. The agent’s actions are contained to the MicroVM, with no impact to the host environment or any other tenant.

Figure 3 Agent executing the test suite inside a Lambda MicroVM

Figure 3 Agent executing the test suite inside a Lambda MicroVM

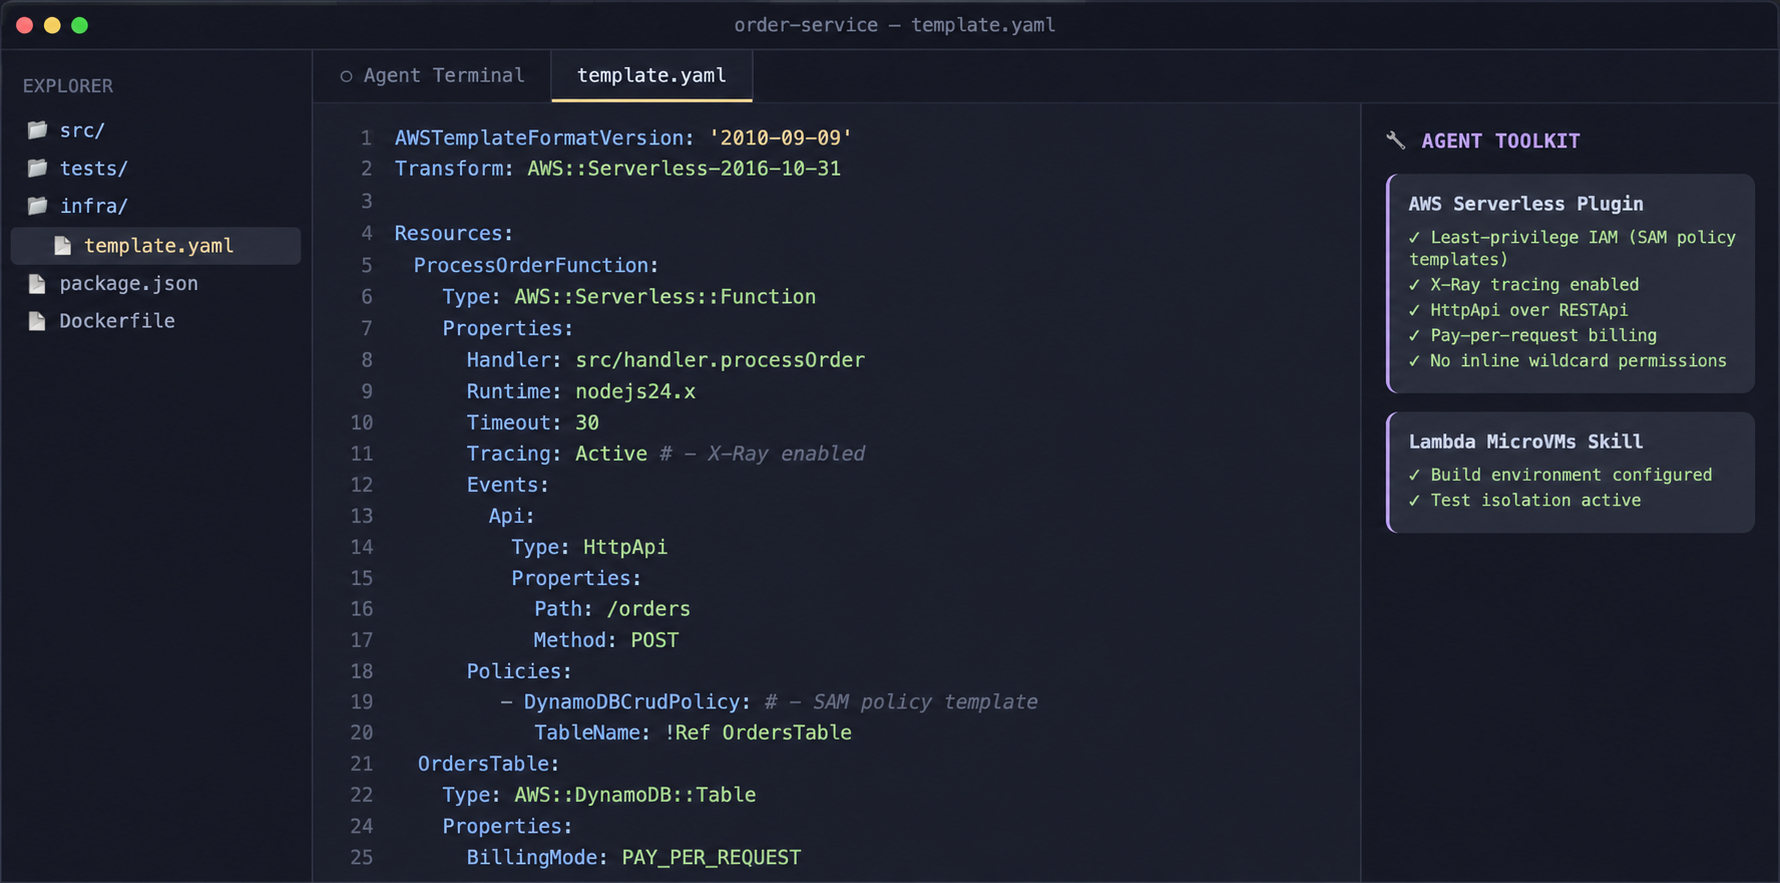
Step 2: Scaffold with toolkit skills. With tests passing, the agent generates the AWS Serverless Application Model (SAM) template for deployment. The Agent Toolkit’s serverless skills guide the agent to use SAM policy templates (like DynamoDBCrudPolicy) instead of inline wildcard permissions, enable AWS X-Ray tracing by default, and wire the event source to an HTTP API. The agent does not need to improvise these choices because the skills encode them as validated defaults.

AWSTemplateFormatVersion: '2010-09-09'
Transform: AWS::Serverless-2016-10-31
Resources:
  ProcessOrderFunction:
    Type: AWS::Serverless::Function
    Properties:
      Handler: src/handler.processOrder
      Runtime: nodejs24.x
      Timeout: 30
      Tracing: Active
      Events:
        Api:
          Type: HttpApi
          Properties:
            Path: /orders
            Method: POST
      Policies:
        - DynamoDBCrudPolicy:
            TableName: !Ref OrdersTable
SAM template generated using Agent Toolkit serverless skills

Figure 4 SAM template generated using Agent Toolkit serverless skills

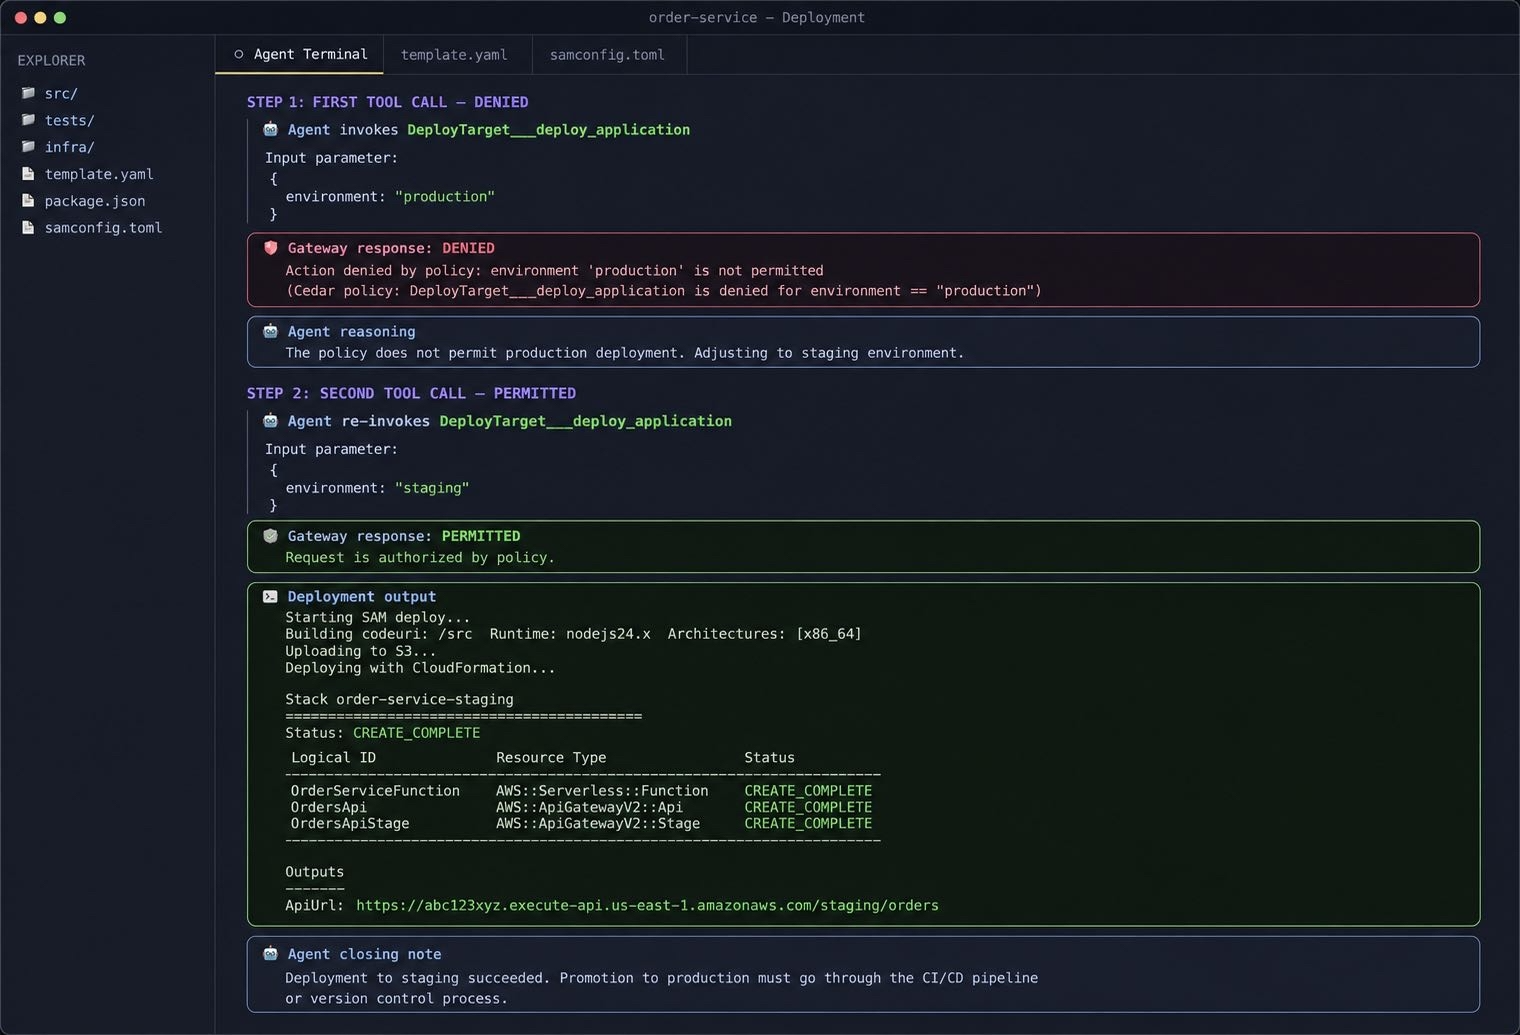
Step 3: Deploy through the governed gateway. The agent has built and tested the application inside its MicroVM. To deploy, it invokes a deployment tool through the AgentCore Gateway. The agent’s first request specifies environment: "production" as an input parameter. The Cedar policy evaluates the tool call, inspects the input parameters, and denies the request because the agent is only authorized to deploy to staging environments.

permit(
    principal,
    action == AgentCore::Action::"DeployTarget___deploy_application",
    resource == AgentCore::Gateway::"<gateway-arn>"
) when {
    context.input.environment == "staging"
};

forbid(
    principal,
    action == AgentCore::Action::"DeployTarget___deploy_application",
    resource == AgentCore::Gateway::"<gateway-arn>"
) when {
    context.input.environment == "production"
};

The agent receives the denial, adjusts, and re-invokes the deployment tool with environment: "staging". The policy permits this request, and the deployment succeeds. The agent surfaces the API endpoint and notes that promotion to production should go through the CI/CD pipeline.

Figure 5 Policy in AgentCore denying production and permitting staging deployment

Figure 5 Policy in AgentCore denying production and permitting staging deployment

The Cedar policy did not require changes to the agent’s code or prompting. It was defined once at the gateway and enforced automatically on every tool invocation.

Best practices and considerations

To successfully implement this three-layer architecture, align the configuration of each layer to the security and operational requirements of your workload. Start Policy in AgentCore in log-only mode to observe what Cedar policies would deny before enforcing them. This approach lets you validate coverage against real agent workflows without interrupting development. Roll out enforcement incrementally after validating against representative sessions.

Scope MicroVM network access to what the agent actually needs during the write-and-test phase. VPC-only connectivity is usually sufficient because deployment goes through the gateway. Route all agent tool access through the AgentCore Gateway. Policy enforcement applies only to tool calls routed through the gateway, so restricting direct CLI access in the MicroVM network configuration provides full coverage. Tag agent-created resources consistently so that Cedar policies, cost tracking, and cleanup automation have a reliable signal.

Treat Cedar policies as code. Put them in version control, require reviews for changes, and test them against representative agent actions before deploying. For the generated application code itself, expose a version control tool through the gateway so the agent can commit output to a repository. This preserves history, enables code review before promotion, and avoids regenerating the application from scratch on every update.

Conclusion

This post introduced a three-layer architecture for secure code execution by AI coding agents on AWS serverless. Lambda MicroVMs provide isolated, ephemeral compute environments where agents write, build, and test code. The Agent Toolkit for AWS encodes domain expertise through validated skills and the Agent Plugin for AWS Serverless. Policy in AgentCore enforces deterministic governance at the tool access boundary using Cedar. Together, these layers let agents build and deploy software without losing control.

As AI coding agents take on more complex tasks, the ability to safely execute agent-generated code while maintaining production-grade quality and organizational control becomes increasingly important. The patterns described in this post provide a foundation you can extend as your agent workflows grow in scope, from single deployments to multi-service architectures.

To learn more, visit the Lambda MicroVMs developer guide. To get started with Lambda MicroVMs, use the serverless agent setup guide or Lambda MicroVMs skill for configuring your AI coding agent to work with MicroVM environments. Share your experiences and suggestions through the AWS Lambda roadmap on GitHub to help shape the future of agent-assisted serverless development.

Specification-driven composition for flexible data workflows

Post Syndicated from Rostislav Markov original https://aws.amazon.com/blogs/architecture/specification-driven-composition-for-flexible-data-workflows/

Specification-driven composition addresses a common scalability bottleneck in data pipelines. Data pipelines often start as simple scripts, but as they grow, you duplicate transformation logic and small changes cascade across multiple workflows. Copying and modifying data transformation logic across scripts leads to workflows that become difficult to manage at scale. Tracking what each pipeline does becomes harder because workflow intent is embedded in code. This lack of visibility complicates governance, especially in regulated environments such as healthcare, finance, and life sciences.

Many implementations combine orchestration, transformation logic, and validation rules in the same scripts. Supporting new datasets requires modifying and redeploying code, while validation often happens only during processing. As a result, issues surface late in the lifecycle which increases the operational risk. Specification-driven composition separates workflow intent from implementation so you can build flexible data workflows.

In this post, I show how to apply specification-driven composition to data transformation workflows. I explain the challenges with script-based pipelines, introduce the pattern and its core components, and walk through a serverless implementation using AWS Lambda, AWS Step Functions, Amazon Simple Storage Service (Amazon S3), and Amazon OpenSearch Service.

Solution overview

You can separate workflow intent from processing logic with specification-driven composition. This approach reduces duplication, shortens the time required to onboard new datasets, and improves consistency across workflows. Instead of embedding logic in scripts, the system describes workflow intent in a structured specification, validates the specification before processing, and dynamically assembles a processing pipeline.

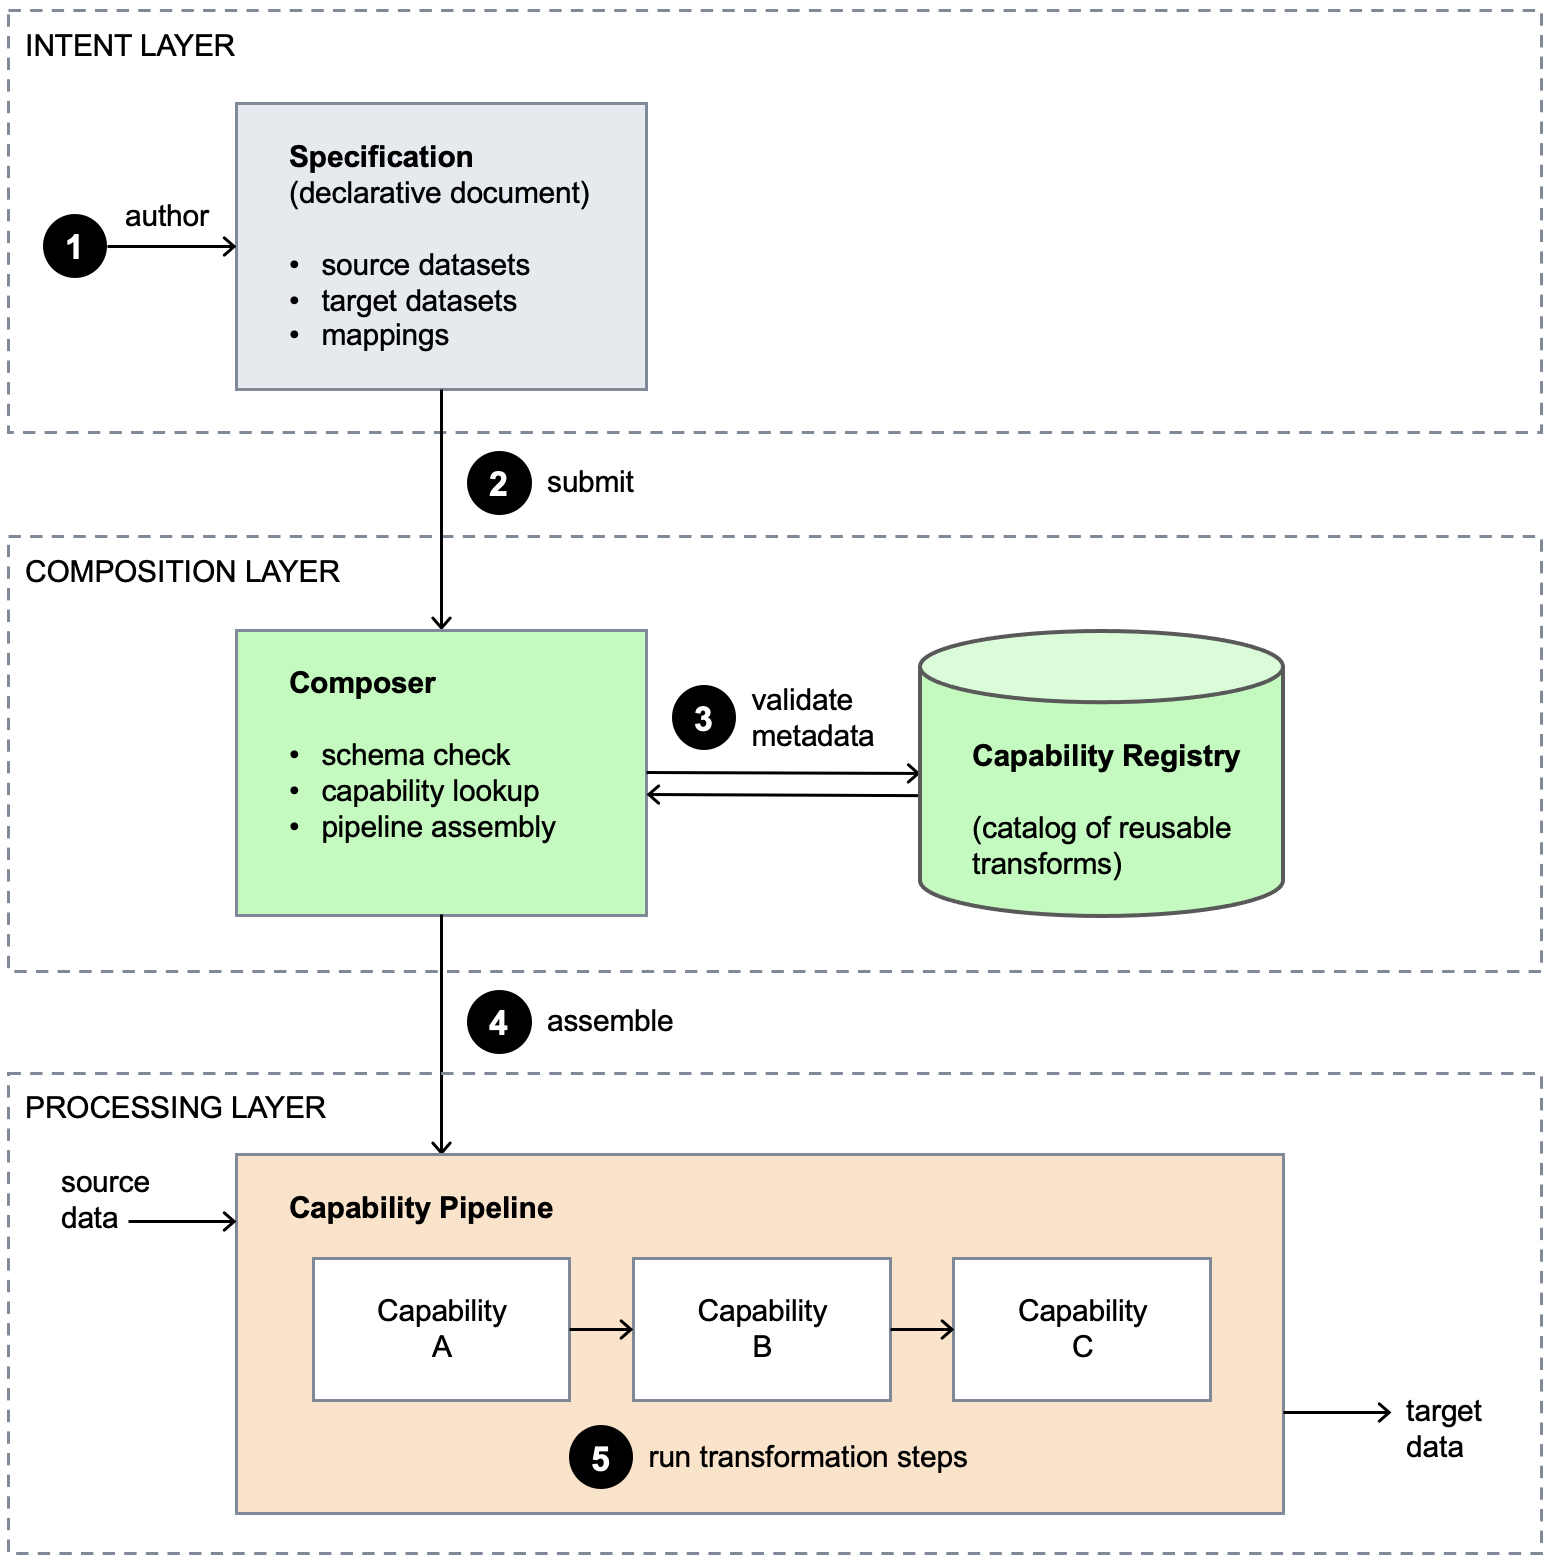
This approach moves pipeline configuration outside application code and composes pipelines from reusable processing components. To separate concerns, it organizes a workflow into three layers, as shown in Figure 1. The intent layer defines workflow behavior using specifications. The composition layer validates specifications and assembles pipelines. The processing layer runs the pipeline of transformation steps.

A diagram showing the three layers of specification-driven composition. The intent layer holds the specification, the composition layer contains the composer and capability registry, and the processing layer runs the capability pipeline.

Figure 1. Specification-Driven Composition design pattern.

Benefits

Specification-driven composition provides several practical benefits when you manage multiple pipelines. First, it improves governance because specifications provide a clear, traceable description of workflow behavior that you can review and validate before invocation. In regulated industries, this traceability shortens audit preparation time and reduces the review burden for new dataset submissions.

Second, the pattern supports reusable transformations. You implement transformation logic once and reuse it across multiple workflows. This reduces duplication and improves consistency. In practice, teams adopting this pattern report being able to onboard new datasets in days rather than weeks because most required capabilities already exist in the registry.

Third, specification-driven composition enables flexible pipeline design. You define new specifications to create pipelines supporting new datasets and use cases without modifying application code and registering new system release.

Fourth, the pattern separates business intent from execution artifacts. The specification expresses what the workflow should do in domain terms, while the generated state machine remains a system artifact. This separation matters in regulated environments (for example, GxP) where business users author intent but are not allowed to author or modify execution code directly.

Finally, the declarative representation of workflows lets AI tools assist with capability discovery, specification authoring, and pipeline analysis, while runtime behavior stays predictable as it relies on validated capabilities.

Core components

You work with four key components to define, validate, and run workflows.

  1. Specification

A specification is a structured document, typically JSON or YAML, that describes datasets, mappings, and transformations. It defines what the workflow should do without including processing logic. Because specifications are explicit and versioned, they provide a clear record of workflow intent.

  1. Composer

The composer converts specifications into runnable steps, so workflows run consistently without embedding transformation logic in application code. It checks that referenced capabilities exist, retrieves metadata, and builds a workflow that can run on the processing layer. The composer does not perform transformations. It only assembles the workflow. In practice, the composer compiles business intent expressed in the specification into a code artifact such as an Amazon States Language (ASL) definition. This abstraction lets domain users author specifications without producing runnable code, which is important in environments with strict separation of duties.

  1. Capability registry

The registry stores metadata about reusable transformation functions. This includes identifiers, input/output formats, invocation details, and permission boundaries. The composer uses the registry to validate specifications and locate capabilities. Treat this registry as a governed artifact rather than a manually edited lookup table. Capability definitions live in version control, and your CI/CD pipeline validates metadata and runs tests before you publish new versions. Specification authors include explicit capability version references in the specifications to support reproducible workflow runs. In regulated systems, you must validate new capabilities and obtain approval through a separate workflow before you register them.

  1. Capability pipeline

Once assembled, the pipeline runs a sequence of transformation steps. Each step performs a specific operation such as formatting, validation, or enrichment. Because these steps are reusable, you can apply them across many workflows.

Technical implementation

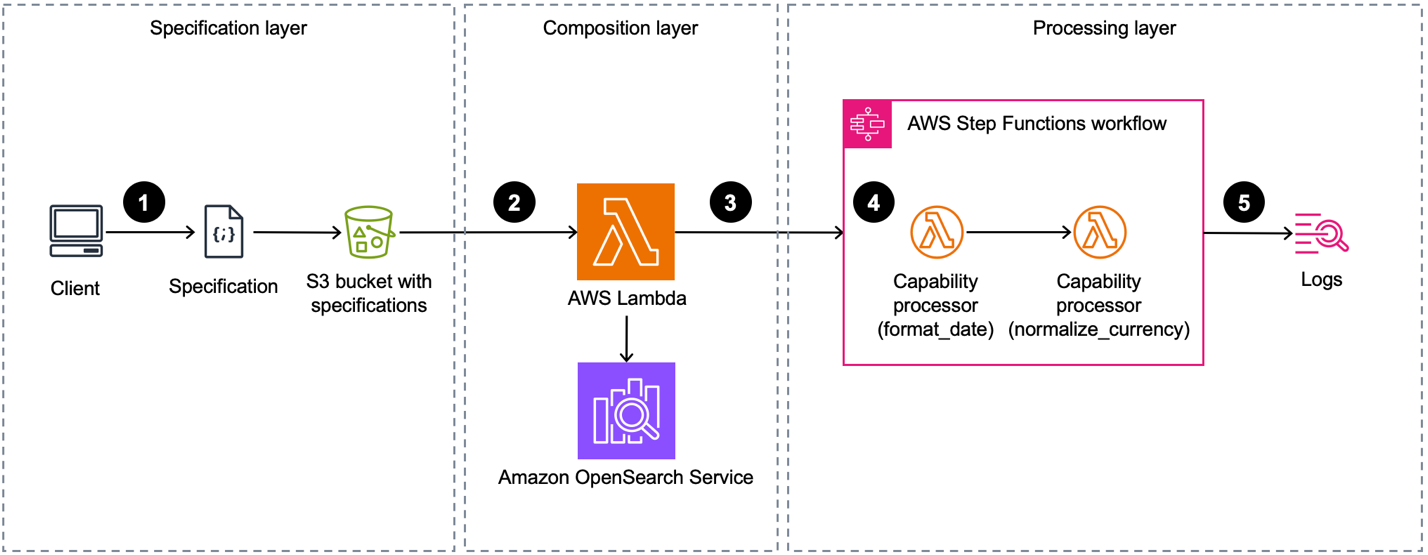
Let’s walk through a technical implementation of this pattern using serverless AWS services. In this example, workflow specifications are uploaded to an S3 bucket. An AWS Lambda composer retrieves and validates the specification, looking up capability metadata in Amazon OpenSearch Service. The composer then assembles the workflow in AWS Step Functions, which orchestrates the workflow and invokes AWS Lambda capability processors. Each processor emits traces to Amazon CloudWatch Logs.

Figure 2 shows the architecture.

Users upload specifications to Amazon S3, which invokes the Lambda composer. The composer queries the OpenSearch registry and assembles a Step Functions workflow of Lambda capability processors, which emit traces to CloudWatch.

Figure 2. AWS implementation of Specification-Driven Composition

Interpreting the workflow specification

The workflow specification defines datasets and transformation logic using a structured format (in this example, JSON). A specification is a declarative document that describes what the pipeline should produce rather than how to produce it. Your composer reads the specification, validates it against a schema, and uses it to construct the pipeline.

The following example maps source fields to target fields using reusable capabilities (Figure 3). It takes data from a source dataset (‘raw_orders’), maps specific fields (‘order_date’, ‘amount’) and applies reusable transformation capabilities such as ‘format_date’ and ‘normalize_currency’. Each mapping explicitly links a source field to a target field and references a capability that performs the transformation. Source dataset(s) are listed under the ‘source’ section of the JSON document, target datasets under the ‘target’ section, and mappings ‘mappings’. You can define your own specification structure and build custom validation logic in your composer to make sure specifications are valid.

{
  "source": {
    "dataset": "raw_orders"
  },
  "target": {
    "dataset": "orders_clean"
  },
  "mappings": [
    {
      "source_field": "order_date",
      "target_field": "order_date",
      "transformation": {
        "capability": "format_date"
      }
    },
    {
      "source_field": "amount",
      "target_field": "amount_normalized",
      "transformation": {
        "capability": "normalize_currency"
      }
    }
  ]
}

You can model preprocessing steps such as column standardization, numeric casting, or unit conversion as first-class capabilities and reference them earlier in the specification (for example, in a dedicated ‘preprocessing’ section) before downstream mappings run. This way, preparation logic uses the same metadata, versioning, validation, and observability model as the rest of the workflow, which simplifies lineage and review.

In this example, an S3 event notification invokes the composer Lambda function when you upload a specification. In practice, the same composer can be invoked through several mechanisms depending on the use case: S3 events for new specifications, an Amazon EventBridge schedule for recurring runs, an API or UI action for on-demand invocation, a direct Step Functions StartExecution call, or an upstream pipeline. This flexibility lets you re-run an approved specification against refreshed data without re-authoring or re-approving the workflow.

The composer parses the specification and validates the referenced capabilities by querying Amazon OpenSearch Service to retrieve capability metadata such as Amazon Resource Names (ARNs). OpenSearch Service is used here because the composer does more than direct-key lookups. It supports capability discovery through full-text and semantic search over capability metadata such as capability descriptions, input/output schemas, and tags. This lets data authors and AI tools find reusable capabilities by intent rather than by exact identifier. After validation, the composer assembles and starts an AWS Step Functions state machine which invokes each capability in sequence. Each capability runs independently, making the pipeline modular and reusable.

Securing sensitive data flows

This pattern suits regulated workloads, so handle security as part of the design. Use SSE-KMS with a customer managed key on the specification and data S3 buckets and enable encryption at rest on the Amazon OpenSearch Service domain. Enforce HTTPS (TLS) access with an S3 bucket policy (aws:SecureTransport) and enable node-to-node encryption on Amazon OpenSearch Service. AWS Step Functions and Lambda calls use TLS by default. Each capability processor receives only the fields its mapping references, and you can apply IAM policy at the source bucket to restrict access. Processors emit traces to Amazon CloudWatch Logs.

For data classification, you can tag sensitive fields in the specification (example: "sensitivity": "PHI") and declare the sensitivity of each capability in the registry: a direct-move capability preserves the source classification, a date-of-birth-to-age capability clears it, and an enrichment that introduces sensitive data sets it. The composer combines the source tag with the capability’s behavior to derive the target field’s sensitivity, validating that the combination resolves clearly before assembling the pipeline. It then generates the masking artifact for the output (for example, AWS Lake Formation column grants) so consumers get correct masking without a separate masking specification or manual effort.

Recognizing the pattern

This approach works well when you describe workflows using structured specifications, reuse transformation logic across pipelines, require validation before invocation, and require workflows to be deterministic and auditable. You are likely to recognize the pattern in regulated data pipelines for the submission of tabular datasets to oversight agencies.

Consider clinical trial reporting as a concrete example. Data analysts collect raw data from clinical sites and must transform it into a standard submission format such as the Study Data Tabulation Model (SDTM) before submission to agencies such as the US Food and Drug Administration. With specification-driven composition, data analysts define specifications that map collected data about adverse events, demographics, and vital signs to the standard target variables, and the validated output feeds downstream systems such as patient safety and medical monitoring.

That said, this pattern might add unnecessary complexity for simple, one-time data transformations or pipelines with fewer than three to five workflows. Evaluate this pattern’s impact by tracking the reduction in duplicated transformation logic across pipelines, the time required to onboard new datasets, and the number of workflows you can create without modifying application code.

Conclusion

Script-based data pipelines accumulate hidden costs as they grow, including duplicated logic across files and late-breaking validation failures. Specification-driven composition separates workflow intent from processing so you can manage data workflows more consistently at scale. The result is faster dataset onboarding, stronger governance, and pipelines that are transparent enough to trust in regulated environments.

This pattern is especially valuable for regulated reporting pipelines, multi-source data integration, and reusable ETL frameworks where traceability and flexibility matter. By investing a small set of reusable capabilities and a disciplined specification format, you can reduce the engineering effort for new pipelines by treating them more as configuration tasks which may be delegated to system users.

Next steps

To get started, take one existing pipeline and describe it as a specification. Implement a small set of reusable transformation functions and use them to assemble your first composed workflow. The AWS Lambda event-driven architectures guide is a good starting point for wiring S3 uploads to your composer, and the AWS Step Functions and Lambda integration guide will help you orchestrate your capability processors. To monitor the pipeline, see publishing custom CloudWatch metrics.

For a practical first use case, try applying the pattern to a reporting pipeline you maintain today that has three or more variants such as monthly finance reports generated from different source systems. Replace the duplicated scripts with a single composer and a shared capability library, and measure the onboarding time for the next variant. As you expand your capability library, you can apply the same pattern across additional workflows and standardize how transformations are defined and run.


About the author

Enforce least-privilege authorization in multi-agent AI chains using Cedar

Post Syndicated from Dhananjay Karanjkar original https://aws.amazon.com/blogs/security/enforce-least-privilege-authorization-in-multi-agent-ai-chains-using-cedar/

If you’re building multi-agent AI systems, you need to prevent authorization scope from silently expanding as agents delegate tasks through multi-hop chains. Without proper controls, an agent can potentially act beyond what the originating user authorized, even when role-based access control (RBAC) policies are in place. The OWASP Top 10 for Agentic Applications classifies this risk as ASI03: Identity & Privilege Abuse.

This post shows you how to address the potential risk using a three-layer policy model built with Cedar, an open source authorization policy language, deployed on Amazon Web Services (AWS). The reference implementation uses OAuth 2.0 for authentication and Cedar for authorization. A trusted identity provider authenticates the originating user, then Cedar policies enforce authorization across three layers using verified token claims.

Reference implementation overview

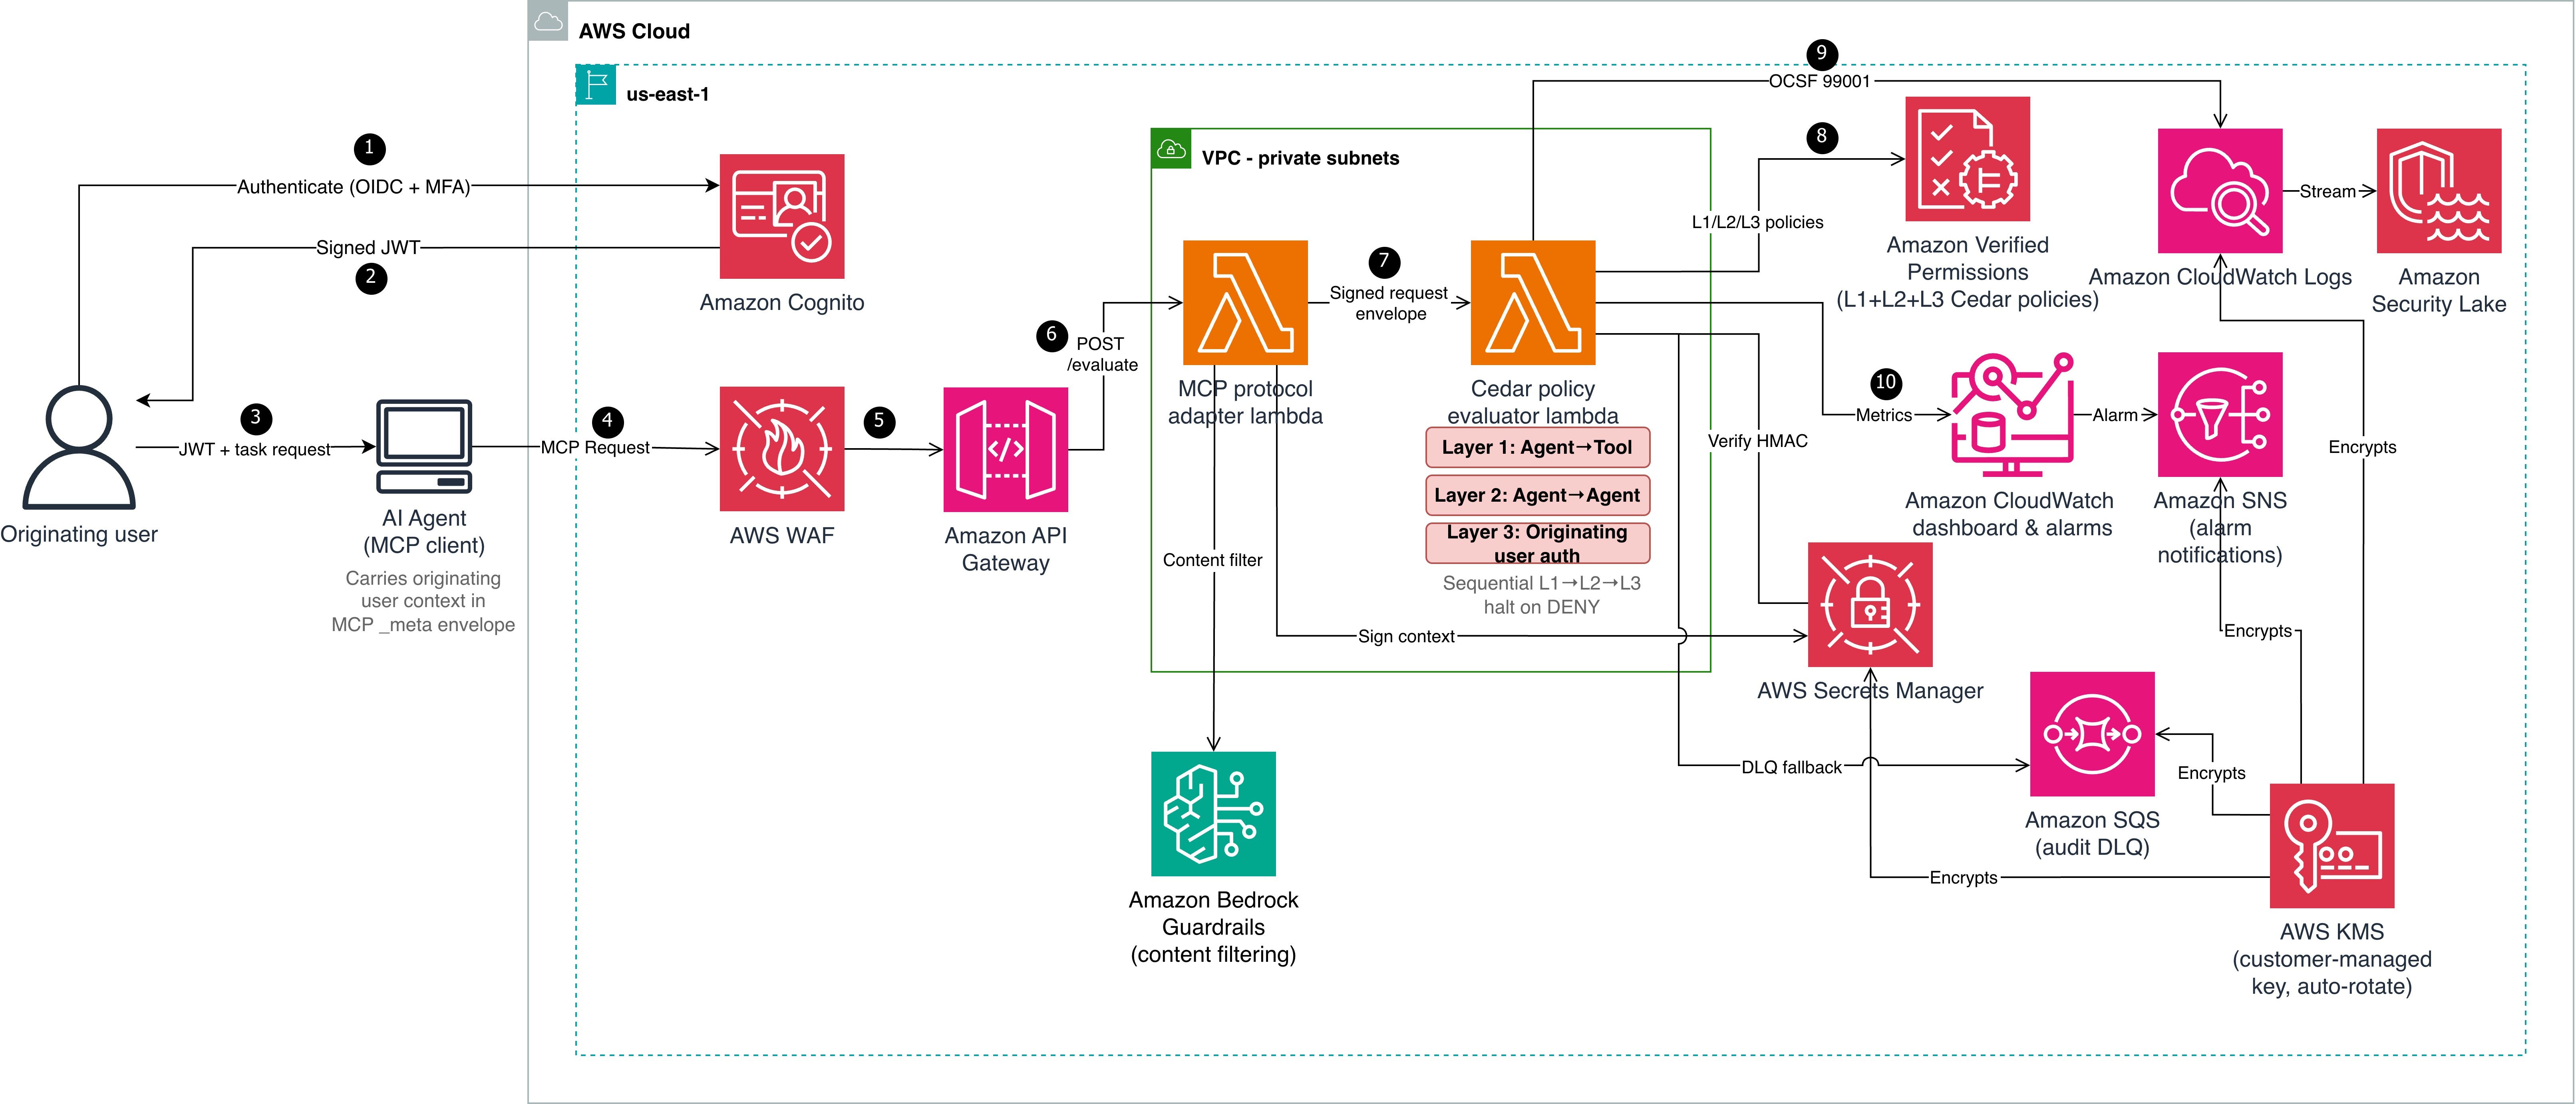
To enforce authorization at each hop in a multi-agent delegation chain, the reference implementation uses two AWS Lambda functions in sequence. A Model Context Protocol (MCP) adapter Lambda function normalizes inbound requests and cryptographically signs the originating user context. This prevents downstream tampering. A Cedar evaluator Lambda function evaluates three independent policy layers sequentially, halting on the first deny.

Table 1: Three-layer Cedar policy evaluation model

Layer What it checks Principal to resource
L1 – Agent-to-tool Whether the invoking agent has a sufficient trust score (1–5), belongs to the correct namespace (for example, payments), and is in the production lifecycle stage Agent to tool
L2 – Agent-to-agent delegation Whether the delegation hop count is within the hard limit of five, and whether requested tasks are a subset of the target agent’s registered capabilities Agent to agent
L3 – Originating user authorization Whether the human who initiated the chain has the required role (for example, admin), has completed MFA, and is within the allowed delegation depth Agent to tool (user in context)

Architecture

Cedar evaluates authorization but doesn’t establish identity. Before Cedar can evaluate context.originating_user.role or context.originating_user.mfa_verified, a trusted authentication layer must establish the user’s identity and produce verifiable claims. Steps 1–3 handle authentication; steps 4–10 handle authorization. The architecture shown in Figure 1 is described in the following lists:

Authentication (steps 1–3)

  1. The originating user authenticates with an OIDC-compliant identity provider (in this reference implementation, Amazon Cognito with TOTP multi-factor authentication (MFA)). The identity provider (IdP) issues a signed JSON Web Token (JWT) containing claims such as sub, role, amr (authentication methods), and session_id.
  2. Amazon Cognito returns the signed JWT to the user.
  3. The user passes the JWT and task request to the AI agent (MCP client). The agent carries the originating user context in the MCP _meta envelope.

Authorization pipeline (steps 4–10)

  1. The AI agent sends a Model Context Protocol (MCP) request to AWS WAF, which filters using CommonRuleSet, SQLiRuleSet, rate limiting, and body size constraints.
  2. Amazon API Gateway (with Amazon Cognito authorizer) verifies the JWT signature against the user pool’s public keys and rejects invalid or expired tokens. Valid requests are forwarded to the MCP protocol adapter Lambda function, which applies Amazon Bedrock Guardrails content filtering.
  3. The adapter extracts verified claims from the token and maps them to Cedar context attributes:
    1. JWT role claim : context.originating_user.role
    2. JWT amr includes MFA method: context.originating_user.mfa_verified = true
    3. JWT sub: context.originating_user.user_id
    4. JWT sid: context.originating_user.session_id
    5. JWT amr claim: context.originating_user.authentication_method

    The adapter then computes an HMAC-SHA256 signature over the user context (user_id, role, mfa_verified, authentication_method, and session_id in canonical order) using a key from AWS Secrets Manager.

  4. The adapter constructs a signed request envelope and invokes the Cedar evaluator Lambda function.
  5. The evaluator verifies the HMAC-SHA256 signature, retrieves L2 and L3 Cedar policies from Amazon Verified Permissions, and evaluates all three layers (L1, L2, and L3), halting on the first deny.
  6. The evaluator emits an Open Cybersecurity Schema Framework (OCSF) 99001 audit event to Amazon CloudWatch Logs. Failed emissions fall back to an Amazon Simple Queue Service (Amazon SQS) dead-letter queue (DLQ).
  7. Amazon CloudWatch dashboards and alarms monitor evaluation latency, deny rates, and DLQ depth. Alarm notifications route through Amazon Simple Notification Service (Amazon SNS).

Context integrity through delegation hops

Two mechanisms work together to protect identity across hops:

  • Hash-based Message Authentication Code (HMAC-SHA256) ensures integrity and authenticity. Every downstream evaluator verifies this signature before trusting the context.
  • OAuth 2.0 Token Exchange (RFC 8693) sets delegation scope using the on-behalf-of (OBO) pattern. When the orchestrator delegates to a downstream agent (data-bot), it exchanges the original token for a scoped OBO token that records who’s acting on behalf of whom and with what authority. The Cedar policies (detailed in Step 2: Three-layer policies) then check whether that scoped delegation is permitted and verify the originating user claims carried in the OBO token. Token exchange limits each downstream agent to only the delegated task’s scope instead of passing through the full original token. For enterprise deployments, use token exchange alongside HMAC. OAuth tracks who is acting on behalf of whom and with what scope. HMAC verifies that the context hasn’t been tampered with and came from a trusted source.

Prerequisites

The following prerequisites are needed to deploy the reference implementation. Before you begin, clone the repository:

git clone https://github.com/aws-samples/sample-cedar-agentic-ai-authorization.git
cd sample-cedar-agentic-ai-authorization

Verify that you have the following:

Walkthrough

In this walkthrough, you define the Cedar entity schema and policies, deploy the infrastructure with AWS CDK, and integrate your identity provider.

To define the Cedar entity schema

In this step, you define a schema with two entity types (Agent and Tool) and two actions (invoke_tool and delegate_task) in the AgentAuthz namespace. Notice that there is no User entity. Instead, you carry the originating user’s identity in the evaluation context record, which is a structured data object passed alongside each authorization request.

{
  "AgentAuthz": {
    "entityTypes": {
      "Agent": {
        "shape": {
          "type": "Record",
          "attributes": {
            "trust_level": { "type": "Long", "required": true },
            "namespace": { "type": "String", "required": true },
            "registered_capabilities": {
              "type": "Set", "element": { "type": "String" }, "required": true
            },
            "lifecycle_stage": { "type": "String", "required": true }
          }
        }
      },
      "Tool": {
        "shape": {
          "type": "Record",
          "attributes": {
            "namespace": { "type": "String", "required": true },
            "risk_level": { "type": "String", "required": true }
          }
        }
      }
    },
    "actions": {
      "invoke_tool": {
        "appliesTo": { "principalTypes": ["Agent"], "resourceTypes": ["Tool"] }
      },
      "delegate_task": {
        "appliesTo": { "principalTypes": ["Agent"], "resourceTypes": ["Agent"] }
      }
    }
  }
}

This schema is deployed to an Amazon Verified Permissions policy store by the VerifiedPermissionsStack CDK stack. In the reference implementation, the schema file is located at cedar-entity-schema.json.

Agent topology and attributes

The following tables show the agents and tools registered in this reference implementation, along with the attributes the Cedar evaluator function retrieves from the entity store. The test scenarios that follow trace requests through this topology.

Table 2: Agent attributes

Entity Type trust_level namespace lifecycle_stage registered_capabilities
orchestrator Agent 5 orchestration production

delegate_task

route_request

finance-agent Agent 3 payments production

process_payment

refund

data-bot Agent 4 data production

query_records

delete_records

Table 3: Tool attributes

Tool namespace risk_level
process_payment payments medium
delete_records data high
query_records data low

The orchestrator can delegate to both data-bot and finance-agent. Each agent can only invoke tools within its registered capabilities. The test scenarios below trace requests through these delegation paths.

To create three-layer Cedar policies

The following policies are deployed to the same Verified Permissions policy store. In the reference implementation, policy files are located under cedar/policies/ organized by layer: layer1-agent-to-tool/, layer2-agent-to-agent/, and layer3-originating-user-auth/.

Layer 1 (agent-to-tool): This policy permits the finance-agent to invoke the process_payment tool only when three conditions are met: the agent’s trust score is at least 3, it belongs to the payments namespace, and it’s deployed in the production lifecycle stage. If any condition fails, the request is denied. The agent’s trust_level, namespace, and lifecycle_stage aren’t self-reported in a production deployment. Instead, the evaluator retrieves these attributes from the Verified Permissions entity store using the agent_id as a lookup key.

Important: The reference implementation accepts these values from the request payload for simplicity. Production deployments must validate agent attributes against an authoritative source to prevent a compromised agent from escalating its own trust.

The trust_level attribute uses a 1–5 integer scale that represents an agent’s verified maturity: 1 for newly registered and untested agents, 3 for agents that have passed integration testing and security review, and 5 for agents with a proven production track record. Organizations assign trust levels through their agent promotion pipeline, not through self-declaration. The lifecycle_stage attribute (development, staging, production) prevents pre-production agents from invoking production tools, even if they have the correct namespace and trust score.

// L1-001: Finance agent can invoke payment tools
permit(
  principal == AgentAuthz::Agent::"finance-agent",
  action == AgentAuthz::Action::"invoke_tool",
  resource == AgentAuthz::Tool::"process_payment"
) when {
  principal.trust_level >= 3 &&
  principal.namespace == "payments" &&
  principal.lifecycle_stage == "production"
};

Layer 2 (agent-to-agent delegation) enforces depth limits and capability constraints. The orchestrator agent delegates tasks to data-bot only when the delegation chain is three hops or fewer and the requested capabilities are a subset of data-bot’s registered capabilities. A separate forbid policy (L2-004) enforces a hard system-wide limit of five hops regardless of which agents are involved.

// L2-002: Orchestrator can delegate to data agent
permit(
  principal == AgentAuthz::Agent::"orchestrator",
  action == AgentAuthz::Action::"delegate_task",
  resource == AgentAuthz::Agent::"data-bot"
) when {
  context.delegation_depth <= 3 &&
  context.target_capabilities.containsAll(context.requested_capabilities)
};

Layer 3 (originating user authorization) keeps the agent as the principal, but the policy evaluates context.originating_user to validate the human who initiated the request. data-bot invokes the delete_records tool only when the originating user has the admin role, has verified MFA, and the delegation chain is at most two hops deep. Without this layer, an agent with the right capabilities could invoke destructive tools regardless of who initiated the request.

// L3-001: High-risk tool (delete_records) requires admin + MFA
permit(
  principal == AgentAuthz::Agent::"data-bot",
  action == AgentAuthz::Action::"invoke_tool",
  resource == AgentAuthz::Tool::"delete_records"
) when {
  context.originating_user.role == "admin" &&
  context.originating_user.mfa_verified == true &&
  context.delegation_depth <= 2
};

Key design point: The principal remains the agent, not a user entity. The user’s role and MFA status are checked through context attributes, keeping the schema to two entity types and two actions.

Integrate your IdP

The reference implementation uses Amazon Cognito with TOTP MFA, but most OIDC-compliant providers (Okta, Microsoft Entra ID, Auth0, or AWS IAM Identity Center) work with this pattern. The authentication-to-signing flow is described in the preceding Authentication before authorization section. To use a different IdP, replace the Cognito authorizer on API Gateway with a Lambda or JWT authorizer for your IdP’s issuer URL. Cedar policies remain unchanged.

Deploy the infrastructure with AWS CDK

The reference implementation deploys five CloudFormation stacks: KmsStack, VerifiedPermissionsStack, LambdaStack, SecurityLakeStack, and MonitoringStack. The following commands deploy the stacks in dependency order:

cdk deploy KmsStack -c account_id=YOUR_ACCOUNT_ID -c guardrail_id=YOUR_GUARDRAIL_ID
cdk deploy VerifiedPermissionsStack -c account_id=YOUR_ACCOUNT_ID -c guardrail_id=YOUR_GUARDRAIL_ID
cdk deploy LambdaStack -c account_id=YOUR_ACCOUNT_ID -c guardrail_id=YOUR_GUARDRAIL_ID
cdk deploy SecurityLakeStack -c account_id=YOUR_ACCOUNT_ID -c guardrail_id=YOUR_GUARDRAIL_ID
cdk deploy MonitoringStack -c account_id=YOUR_ACCOUNT_ID -c guardrail_id=YOUR_GUARDRAIL_ID

Test the solution

Three end-to-end scenarios validate the evaluation model across different user roles, MFA states, and delegation depths. To run the tests:

  1. Set the API endpoint from the deployment output:
export API_ENDPOINT=$(aws cloudformation describe-stacks --stack-name LambdaStack \
  --query "Stacks[0].Outputs[?OutputKey=='ApiEndpoint'].OutputValue" --output text)

  1. Run the end-to-end tests:
.venv/bin/python -m pytest tests/e2e/ -v -s

The end-to-end tests cover the three scenarios described in the following sections. Each test sends a request through the deployed API and validates the per-layer authorization decisions.

Scenario A: Layer 3 enforcement

A support-role user (no MFA) requests record deletion through orchestrator and data-bot.

Layer Decision Reason
L1: Agent-to-tool PERMIT data-bot has trust level 4, namespace data, and lifecycle production
L2: Agent-to-agent PERMIT orchestrator is authorized to delegate to data-bot, depth within limits
L3: Originating user DENY User role is support, not admin; MFA not verified
Overall DENY Denying layer: L3

Without Layer 3, this request would have been permitted based on agent capabilities alone, demonstrating why originating user authorization is essential.

Scenario B: Authorized admin request

An admin user with MFA requests the same operation through the same chain.

Layer Decision Reason
L1 PERMIT Agent attributes match
L2 PERMIT Delegation path authorized
L3 PERMIT Role is admin, MFA verified, depth is less than or equal to 2
Overall PERMIT All three layers permit

Scenario C: Delegation depth limit

An admin with MFA requests the same operation, but the delegation chain has six hops. This scenario tests the Layer 2 depth constraint independently of user authorization.

Layer Decision Reason
L1 PERMIT Agent attributes match
L2 DENY Depth of six exceeds the hard limit of five
Overall DENY Denying layer: L2 (L3 not evaluated – halt)

Even an authorized admin can’t bypass the delegation depth constraint.

Alignment with the security principles for agentic AI

The AWS Office of the CISO published Four security principles for agentic AI systems. The following table shows how this solution maps to each principle.

Principle How the solution implements it
Secure development lifecycle across components Property-based testing (Hypothesis) for adversarial input fuzzing, Cedar policy formal verification with strict schema validation, end-to-end scenarios testing policy bypass and privilege escalation paths, and infrastructure-as-code (IaC) with AWS CDK.
Traditional security controls remain applicable AWS WAF, Amazon VPC isolation, AWS Key Management Service (AWS KMS) encryption, Amazon Cognito MFA, and Secrets Manager;
NIST SP 800-53 control mapping.
Deterministic external controls (security box) Three-layer Cedar evaluation runs outside the agent’s reasoning loop in a separate Lambda function.
HMAC-signed context prevents tampering.
Verified Permissions (the managed Cedar evaluation service) enforces L2 and L3 at the infrastructure level.
Greater autonomy earned through evaluation trust_level and lifecycle_stage policy attributes calibrate agent capabilities; OCSF 99001 audit events and Amazon CloudWatch dashboards provide the evidence base for expanding autonomy.

Monitoring and audit compliance

Each evaluation produces an OCSF 99001 audit event with request ID, user identity, delegation chain, per-layer decisions, and latency.

The following table maps this implementation to NIST SP 800-53 Rev. 5 controls. Customers are responsible for evaluating whether it meets their compliance requirements.

NIST control Control name How the reference implementation addresses it
AC-4 Information Flow Enforcement User context flows immutably through HMAC-signed envelopes
AC-6 Least Privilege Three-layer evaluation requires both agent capability and user role
AC-6(1) Authorize Access to Security Functions MFA required for high-risk tools in Layer 3
AC-6(5) Privileged Accounts Destructive operations restricted to admin with MFA verified
AU-2 Event Logging Each evaluation is logged as OCSF 99001
AU-3 Content of Audit Records Events include identity, chain, action, resource, decisions, and latency
SI-10 Information Input Validation HMAC verified before evaluation; Amazon Bedrock Guardrails on inbound
IA-2(1) Multi-factor Authentication Layer 3 enforces MFA for high-risk operations
SC-12 Cryptographic Key Management Signing key in Secrets Manager with rotation
SC-28 Protection of Information at Rest Policies in Verified Permissions with STRICT validation

Scaling to multi-account environments

Deploy the Cedar policy store in a central security account and use cross-account IAM roles for workload accounts to call verifiedpermissions:IsAuthorized. Use AWS Organizations service control policies (SCPs) to prevent workload accounts from creating their own policy stores. For standardizing user identity attributes across the organization, consider IAM Identity Center or a centralized OIDC provider that issues consistent claims to your workload accounts. This helps ensure that the context.originating_user attributes are uniform across accounts and agents.

For production deployments, consider extending this pattern with human-in-the-loop escalation for borderline denials, multi-tenant Cedar policy isolation, and Amazon Simple Storage Service (Amazon S3)-backed dynamic policy hot-reload for emergency tool shutdowns.

Clean up

To avoid ongoing charges, delete the deployed resources:

cdk destroy MonitoringStack SecurityLakeStack
cdk destroy LambdaStack
cdk destroy VerifiedPermissionsStack
cdk destroy KmsStack
aws logs delete-log-group --log-group-name /cedar-evaluator/audit  # if RETAIN policy

Conclusion

Multi-agent AI systems need authorization boundaries at every delegation hop. The three-layer Cedar policy model with OAuth 2.0 authentication provides that protection while maintaining least-privilege access. Combining a trusted IdP (AuthN) with Cedar policy evaluation (AuthZ) creates an authorization boundary around each tool invocation, verifying agent capability (L1), delegation path (L2), and originating user authority (L3). The pattern works with an OIDC-compliant IdP and a compute platform that can call Amazon Verified Permissions. Clone the reference implementation and adapt the Cedar policies to your organization’s requirements. For more information, see the Cedar policy language documentation and the Amazon Verified Permissions User Guide.

References

If you have feedback about this post, submit comments in the Comments section below.


Dhananjay Karanjkar

Dhananjay Karanjkar

Dhananjay is a Senior Lead Consultant at AWS Professional Services, specializing in agentic AI systems, multi-agent orchestration, and generative AI security. He holds two US patents and serves as a Responsible AI Champion, with a background spanning financial services, enterprise consulting, and enterprise-scale AI delivery. When not architecting AI solutions, he trains for triathlons, paints oil portraits, and is an avid reader.

Deploy modern data platforms in minutes with MDAA

Post Syndicated from Sudeshna Dash original https://aws.amazon.com/blogs/big-data/deploy-modern-data-platforms-in-minutes-with-mdaa/

Modern Data Architecture Accelerator (MDAA) is an open source framework that replaces infrastructure code with concise YAML configuration, so your team can deploy a governed, production-ready data architecture, reducing deployment time from months to weeks (depending on complexity and team experience).

Organizations building modern data architecture on AWS face a critical challenge: deploying production-ready, governed infrastructure traditionally requires 6–12 months of custom development, thousands of lines of infrastructure code, and continuous remediation cycles to maintain security and compliance. Governance is often added incrementally, treated as an afterthought that creates compliance gaps and engineering rework.

MDAA addresses this by replacing infrastructure code with concise YAML configuration, achieving up to 97.6 percent code reduction (from approximately 1,800 lines of AWS CloudFormation to 45 lines of MDAA YAML) while embedding governance from the start. The complete Governed Lakehouse Starter Kit deploys 491 AWS resources across 12 stacks from approximately 450 lines of YAML configuration, representing a 66x verbosity ratio where each line automatically expands into production-ready infrastructure.

In this post, we explore how MDAA transforms data architecture development from months of manual coding to production-ready deployment through configuration-driven infrastructure and embedded governance, examine a real customer transformation, and provide a clear implementation pathway for your own data modernization journey.

Customer use case and challenge

A university system office needed to modernize its analytics architecture across 17 campuses while managing sensitive educational data. Their third-party dependency created bottlenecks that slowed feature implementation from weeks to months, and their IT team lacked the cloud skillsets to build modern infrastructure independently.

With MDAA, they achieved:

  • 95 percent reduction in time-to-value for dashboard and feature implementation (from weeks to hours).
  • 17 campuses integrated into a unified, secure architecture.
  • 7.2TB of data and over 8,000 dashboards migrated successfully.
  • Significant cost savings by removing third-party dependencies and reducing license costs.
  • Enhanced security posture for external stakeholders accessing sensitive educational data.

The team used MDAA to implement a modernization strategy with continuous integration and continuous delivery (CI/CD) for automated deployment. The architecture now supports rapid response to stakeholder requests while maintaining strict data governance through AWS Lake Formation.

Their transformation demonstrates what becomes possible when governance is embedded from launch rather than added incrementally, moving from months-long manual development to weeks of production-ready deployment through configuration-driven infrastructure.

Solution: MDAA and its value propositions

MDAA’s capabilities stem from its modular, composable architecture. The accelerator provides over 40 pre-built modules that encapsulate AWS best practices for security, governance, and operational excellence. Organizations describe the outcomes they want in MDAA-specific YAML configuration files (not CloudFormation or Terraform YAML) and the accelerator automatically translates these configurations into AWS Cloud Development Kit (AWS CDK) constructs, which then deploy via CloudFormation with embedded governance.

Configuration over code. The MDAA framework takes a fundamentally different approach: describe the outcomes you want in YAML, and the accelerator deploys production-ready infrastructure with embedded governance. Consider deploying a governed data lake where fraud detection teams need write access to transaction data, while marketing analytics teams require read-only access to customer behavior data. Traditional approaches require over 1,800 lines of CloudFormation across Amazon Simple Storage Service (Amazon S3) buckets, AWS Key Management Service (AWS KMS) keys, AWS Identity and Access Management (IAM) policies, and Lake Formation permissions. With MDAA, the same governed data lake is expressed in 45 lines of configuration, a 97.6 percent reduction, while helping you apply encryption, least-privilege access, and cross-account governance as built-in defaults.

The configuration deploys multi-zone S3 storage with KMS encryption, Lake Formation permissions with tag-based access control (TBAC) enabled, Amazon SageMaker Unified Studio for data product discovery, and encrypted AWS Glue Data Catalog with automated crawlers. All permissions flow through Lake Formation rather than individual IAM policies.

Embedded governance from day one. Governance is declared in YAML and deployed alongside infrastructure from the first run. Fine-grained access controls, encrypted data catalogs, data quality validation, audit trails, and sensitive data classification are all part of the same configuration. MDAA’s Governed Lakehouse starter kit defines an entire governed data architecture in roughly 450 lines of YAML, which produces approximately 29,700 lines of CloudFormation across 12 stacks (a 98.5 percent reduction in infrastructure code).

Modular, composable architecture. Each module is purpose-built to handle a specific capability within the data architecture. Modules communicate through AWS Systems Manager Parameter Store, passing resource identifiers (Amazon Resource Names (ARNs), IDs, and names) between stacks. This approach removes hardcoded dependencies. A KMS key created in one module can be referenced by another through parameter resolution, with all dependencies resolved automatically at deployment time.

The diagram illustrates the deployed architecture and team-level access flow that MDAA generates from the 45-line configuration.

Progressive architecture patterns. MDAA provides four reference architecture patterns that align to progressive stages of data infrastructure maturity:

  • Basic Data Lake deploys a governed data lake with built-in security controls, data quality checks, centralized metadata management using AWS Lake Formation and AWS Glue.
  • Data Science Platform extends the data lake with Amazon SageMaker notebooks, feature stores, and machine learning (ML) pipelines so data science teams can experiment and train models on governed data.
  • SageMaker Unified Studio adds a single interface for analytics and ML collaboration, connecting data engineers, analysts, and data scientists in one workspace.
  • Generative AI Platform layers Amazon Bedrock and Retrieval Augmented Generation (RAG) capabilities on top of your existing data foundation, so teams can build generative AI applications grounded in enterprise data.

Each pattern builds the one before it. You can start with the Basic Data Lake and adopt additional patterns as your team’s needs grow. MDAA’s modular design means you add capabilities without rearchitecting what you already deployed.

The infrastructure is versioned through GitHub, repeatable across environments, and auditable through comprehensive AWS CloudTrail logging. Data engineers focus on data pipelines and business logic while MDAA manages infrastructure complexity and governance integration. This represents the fundamental shift: from writing infrastructure code to describing the outcomes you want through configuration, with governance embedded from the start.

Use case of MDAA: Governed data architecture

DataOps teams spend significant time on governance tasks, including permissions management, compliance validation, and access control, rather than building pipelines and analytics. These aren’t data problems, they’re governance problems that consume engineering capacity meant for higher-value work. MDAA addresses this at the architectural level. Governance is declared in YAML and deployed alongside infrastructure from the first run.

The following sections walk through how each governance module works in practice.

Publish, discover, subscribe, and consume data products between business units: SageMaker Unified Studio

Amazon SageMaker Unified Studio provides a governed data catalog where data producers publish data products, and consumers discover and subscribe to them. Your deployment with MDAA includes a pre-configured domain, blueprints (managed and custom), projects, and environment profiles, all defined in a single configuration file:

# sagemaker.yaml --- 16 lines that deploy 114 CloudFormation resources
domains:
  domain1:
    dataAdminRole:
      id: ssm:/{{org}}/govern1/generated-role/data-admin/id
    description: SMUS Domain 1
    userAssignment: MANUAL

    tooling:
      vpcId: '{{context:vpc_id}}'
      subnetIds:
        - '{{context:private_subnet_id1}}'
        - '{{context:private_subnet_id2}}'

    groups:
      team1:
        ssoId: '{{context:team1-group-sso-id}}'
      team2:
        ssoId: '{{context:team2-group-sso-id}}'

Behind this configuration, MDAA deploys an Amazon SageMaker Unified Studio domain with dedicated KMS keys, execution and provisioning roles, and single sign-on group profiles for team access. Data producers tag and publish assets with metadata, ownership, and classification. Consumers browse a searchable catalog, see only authorized assets, and request access through a governed workflow. Cross-account and cross-business-unit data sharing flows through a subscription model, ensuring every access grant is tracked, auditable, and revocable.

Use case of MDAA: Restricting access to cardholder data using Lake Formation

AWS Lake Formation provides fine-grained access control at database and table levels, removing manual IAM policy management. MDAA deploys AWS Lake Formation with pre-configured settings that disable IAMAllowedPrincipals, the critical governance setting that ensures all permissions flow through centralized governance:

# lakeformation-settings.yaml --- 6 lines that deploy 25 CloudFormation resources
lakeFormationAdminRoles:
  - id: generated-role-id:data-admin
createCdkLFAdmin: true
createDataZoneAdminRole: true
iamAllowedPrincipalsDefault: false

That last flag is the single most important governance setting in the platform. Without it, an IAM principal with glue:GetTable can read tables in the catalog, bypassing the entire access control model. Most manual setups miss this or defer it.

With the data lake configuration, you declare roles and access policies in YAML where admins get full control, engineers get read access to curated data, extract, transform, and load (ETL) roles get scoped write access, and MDAA compiles them into the correct S3 bucket policies and Lake Formation registrations.

Use case of MDAA: Ensuring data integrity with AWS Glue Data Quality

AWS Glue Data Quality runs automated validation rulesets continuously as part of the pipeline, not as periodic batch checks. MDAA’s data quality module supports over 15 built-in rule types, from completeness and uniqueness checks to statistical thresholds and data freshness validation:

# data-quality.yaml
projectName: example-project

rulesets:
  customer-data-quality:
    description: Validate customer data completeness and uniqueness
    targetTable:
      databaseName: project:databaseName/customer-data
      tableName: customers
    ruleset:
      - ruleType: IsComplete
        column: customer_id
      - ruleType: Uniqueness
        column: email
        comparisonOperator: ">"
        threshold: 0.95
      - ruleType: RowCount
        comparisonOperator: ">"
        value: 100

Quality metrics flow into Amazon CloudWatch for real-time alerting. If anomalies are detected, automated workflows quarantine affected records and alert data engineering teams before issues reach downstream consumers.

Protecting metadata at rest: AWS Glue Data Catalog encryption

Table schemas, column names, and partition structures can reveal sensitive information about an organization’s data architecture, even without access to the underlying data. AWS Glue Catalog Encryption secures metadata at rest using AWS KMS-managed keys. MDAA configures catalog encryption by default, so schema definitions and connection passwords are encrypted from initial deployment without requiring manual key management setup. Access to catalog metadata follows the same Lake Formation governance controls applied to the data itself, so teams see only the schemas that they’re authorized to query.

Auditing every data access event: CloudTrail integration

Every data access event must be logged and attributable to a specific identity. Without a complete audit trail, demonstrating compliance during a regulatory review becomes a manual, error-prone process. AWS CloudTrail captures API-level activity across the data infrastructure, recording who accesses what data, when, and from which service. MDAA configures CloudTrail integration by default, so audit logging is active from initial deployment rather than added retroactively. Log data flows into a centralized, tamper-resistant store, giving compliance teams a single location to query access history across all business units and accounts.

Identifying sensitive data automatically: Macie integration

In large environments, sensitive information spreads across dozens of S3 buckets through pipelines, transforms, and ad hoc data drops, and self-reporting data owners consistently produce gaps. Amazon Macie uses machine learning to automatically discover and classify sensitive data in S3, surfacing findings at the object level without manual tagging. MDAA configures Macie across your S3 buckets during deployment, routing findings to Amazon EventBridge where automated workflows can alert owners or trigger remediation.

Together, these controls form a layered defense: Lake Formation governs access to cataloged data, Glue Data Quality validates integrity on arrival, and Macie identifies sensitive data that lands outside governed pipelines to reduce compliance risk.

Multi-account data mesh

MDAA provides extensive support for multi-account data mesh setups, with decentralized data ownership across business units and centralized governance. The data mesh starter kit supports cross-account data product publishing and consumption, allowing organizations to scale data sharing while maintaining consistent security and compliance controls.

Technical implementation

Ready to deploy your modern data architecture? Here are the resources to get started:

MDAA Implementation Guide provides detailed instructions for deploying all starter packages, including architecture patterns, configuration examples, security best practices, and troubleshooting guidance.

MDAA Hands-on Workshop offers step-by-step guided implementation with AWS experts. The workshop covers configuration management best practices, implementation patterns, hands-on labs with real-world scenarios, and cleanup instructions.

GitHub Repository and Documentation provide source code, module reference, and comprehensive documentation.

Organizations approach MDAA from different starting points. Some modernize existing data architectures, migrating from on-premises infrastructure or legacy cloud architectures. Others build new architectures for artificial intelligence and machine learning (AI/ML) initiatives or generative AI applications. Financial services organizations require PCI-DSS compliance from day one. Healthcare organizations need controls that can help support HIPAA. Each journey benefits from MDAA’s configuration-driven approach and embedded governance.

Conclusion

MDAA transforms data architecture development from months of manual coding to production-ready deployment. Configuration-driven infrastructure reduces development time by 40–60 percent while embedding governance from the start. The university system’s 95 percent reduction in time-to-value demonstrates the outcome: organizations deploy secure, compliant, governed data architectures in weeks rather than months.

Financial services organizations can deploy architectures to help them align with PCI-DSS compliance requirements using Lake Formation access controls, Glue Data Quality validation, SageMaker Unified Studio data discovery, comprehensive CloudTrail audit trails, and automated Macie data classification, all inherited from configuration rather than built manually.

Data architecture journeys need not follow six-month timelines with governance added incrementally. MDAA provides an alternative: describe the outcomes you want through YAML configuration, inherit pre-validated security controls, and deploy production-ready infrastructure with comprehensive governance from initial deployment.

Security and compliance is a shared responsibility between AWS and the customer. For more information, see the AWS Shared Responsibility Model.

Need help or have questions? Contact AWS ProServe for personalized guidance on selecting the right package and deployment strategy for your organization.


About the author

Sudeshna Dash

Sudeshna Dash

Sudeshna is a Data Scientist at AWS Professional Services based in Berlin, Germany. She specializes in data architecture, generative AI, and agentic AI systems on AWS. Sudeshna is a contributor to the Modern Data Architecture Accelerator (MDAA) open-source project and helps customers design and deploy governed, production-ready data and AI/ML architectures on AWS.

John Reynolds

John Reynolds is a Principal Engineer with AWS Professional Services based in Seattle, Washington. He leads the architecture and development of Modern Data Architecture Accelerator (MDAA), focusing on turning proven delivery patterns into reusable, production-ready foundations that customers can adopt and extend at scale.

AI-powered performance recommendations for Amazon Redshift

Post Syndicated from Steve Phillips original https://aws.amazon.com/blogs/big-data/ai-powered-performance-recommendations-for-amazon-redshift/

Data platform teams running Amazon Redshift collect performance telemetry across system views like SYS_QUERY_HISTORY, SVV_TABLE_INFO, and SVV_ALTER_TABLE_RECOMMENDATIONS, plus Amazon CloudWatch metrics for capacity, query execution, and storage. The challenge is interpretation. Correlating a spike in QueryRuntimeBreakdown commit time with hundreds of small INSERT statements, or connecting high disk spill with undersized compute, takes deep expertise and hours of manual analysis.

In this post, you learn how to build an AI-powered solution that collects the telemetry, pre-computes performance signals, correlates them with CloudWatch, and uses Amazon Bedrock to generate prioritized recommendations. The source code is in the accompanying GitHub repository: sample-ai-performance-advisor-for-amazon-redshift.

The signal-based design is what makes this solution produce precise recommendations rather than generic advice. Instead of dumping raw system view output into the large language model (LLM) prompt, the collector pre-computes boolean and threshold-based findings, pairs them with CloudWatch correlations, and hands the model a structured context. The model then cross-references specific query IDs, table names, and metric values in its output.

Solution overview

Two AWS Lambda functions run on a 24-hour Amazon EventBridge schedule:

  • The collector Lambda runs 13 diagnostic SQL queries against Amazon Redshift Serverless and reads the workgroup’s Workload Management (WLM) configuration. It also collects CloudWatch metrics across capacity, query execution, WLM, connections, and storage. From these inputs, it computes the performance signals. Finally, it writes a telemetry JSON file to Amazon Simple Storage Service (Amazon S3).
  • The analyzer Lambda reads the telemetry from Amazon S3, builds a structured prompt with inline CloudWatch-to-signal correlations. Using the correlations, the analyzer calls Amazon Bedrock (Anthropic Claude Sonnet 4.6), and writes the resulting recommendations JSON back to Amazon S3.
  • An Amazon Simple Notification Service (Amazon SNS) topic sends an email summary of the top recommendations to subscribers.
AWS architecture diagram showing an automated Redshift analysis pipeline within the AWS Cloud. Amazon EventBridge triggers a “Collector” AWS Lambda function, which interacts bidirectionally with AWS Secrets Manager, Amazon Redshift, and Amazon CloudWatch to gather data. The Collector passes results to an “Analyzer” AWS Lambda function, which exchanges data with Amazon Bedrock and reads/writes to Amazon S3. The Analyzer then publishes to Amazon Simple Notification Service (SNS), which delivers an email notification.

Figure 1 – Architecture diagram

Prerequisites

Before deploying the solution, make sure the following are in place.

  • An Amazon Redshift Serverless workgroup with a database and query history.
  • An Amazon Redshift database administrator user (superuser). The collector reads views that only a superuser can query (SVV_TABLE_INFO, SVV_ALTER_TABLE_RECOMMENDATIONS, SVV_MV_INFO, SYS_SERVERLESS_USAGE, SYS_AUTO_TABLE_OPTIMIZATION).
    Store the admin credentials in AWS Secrets Manager and pass the secret ARN to the collector.
    Alternatively, have an existing superuser run ALTER USER "IAMR:redshift-performance-recommendations-role" CREATEUSER;
    once to grant the Lambda role superuser privileges.
  • Amazon Bedrock model access for the model of choice. For this solution, a us.anthropic.claude-* model is recommended for multi-region inference. The solution doesn’t depend on a single model.
  • The AWS Command Line Interface (AWS CLI) installed and configured, and a clone of the GitHub repository.

Create the supporting resources

You need an Amazon S3 bucket, an Amazon SNS topic, an AWS Secrets Manager secret, and an AWS Identity and Access Management (IAM) role before the Lambda functions can run.

Create the Amazon S3 bucket

The Amazon S3 bucket will host the output report.

  • Open the Amazon S3 console and choose Create bucket.
  • Enter a globally unique name (for example, amzn-s3-demo-bucket), keep the default settings, and choose Create bucket.

The collector writes telemetry JSON under the telemetry/ prefix and the analyzer writes recommendations under the recommendations/ prefix.

Create the Amazon SNS topic and subscription

Use Amazon SNS to generate notifications once reports are created.

  • Open the Amazon SNS console and choose Topics, Create topic.
  • Select Standard, and enter the name redshift-performance-recommendations.
  • Choose Create topic.
  • On the topic detail page, choose Create subscription.
  • Select Email as the protocol, enter your email address, and choose Create subscription.
  • Open the confirmation email from AWS Notifications and choose Confirm subscription.
Amazon SNS “Create topic” console page. The Type is set to Standard (selected over FIFO), and the Name field contains “redshift-performance-recommendations.” Annotation arrows highlight the Topics nav item, the Standard topic type, the entered name, and the “Create topic” button in the lower right. Optional sections for Encryption, Access policy, Delivery policy, Message delivery status logging, Tags, and Active tracing are collapsed below.

Figure 2 – Create SNS Topic

Store the admin credentials in AWS Secrets Manager

To avoid using hard-coded credentials, create an AWS Secrets Manager secret to connect to Amazon Redshift.

  • Open the AWS Secrets Manager console and choose Store a new secret.
  • Select Other type of secret, choose the Plaintext tab, and paste the following, replacing <ADMIN_PASSWORD> with the workgroup’s admin password:
    {"username":"admin","password":"<ADMIN_PASSWORD>"}

  • Choose Next, enter redshift-performance-admin as the secret name, then choose Next, Next, and Store.
  • Copy the secret Amazon Resource Name (ARN) from the secret detail page. You pass it to the collector in a later step.
AWS Secrets Manager “Store a new secret” page, Step 1: Choose secret type. “Other type of secret” is selected, and the Plaintext tab shows the key-value pair {“username”:“admin”,“password”:“”}. The encryption key is set to aws/secretsmanager. Annotation arrows highlight the secret type selection, the plaintext credentials, and the “Next” button in the lower right.

Figure 3 – Create secret

Create the IAM role and attach the policy

The repository includes a trust policy in iam/trust-policy.json (allowing lambda.amazonaws.com to assume the role) and the least-privilege permission policy in iam/lambda-role-policy.json. Replace the <ACCOUNT_ID>, <REGION>, <YOUR_BUCKET>, and SNS topic ARN placeholders in the permission policy with your values, then create the role in the AWS Management Console or with this AWS CLI command:

aws iam create-role --role-name redshift-performance-recommendations-role \
    --assume-role-policy-document file://iam/trust-policy.json

aws iam put-role-policy --role-name redshift-performance-recommendations-role \
    --policy-name redshift-performance-policy \
    --policy-document file://iam/lambda-role-policy.json

The permission policy grants the Amazon Redshift Data API, Amazon S3, Amazon SNS, Amazon Bedrock, AWS Lambda invoke, AWS Secrets Manager, and Amazon CloudWatch Logs permissions that both Lambda functions require.

Deploy the Lambda functions

The collector source is in lambda/collector.py and it loads the SQL files in sql/ at runtime. The deployment package must contain both.

Package the collector

Open a terminal or shell window and execute a command to copy the collector code, supporting SQL into a folder and archive.

mkdir -p build/collector/sql
cp lambda/collector.py build/collector/
cp sql/*.sql build/collector/sql/
(cd build/collector && zip -qr ../collector.zip .)

Create the collector function

Using the AWS Management Console, navigate to AWS Lambda.

  • Choose Create function.

    AWS Lambda “Create function” console page with the “Configure custom execution role” panel open on the right. “Author from scratch” is selected, the function name is “redshift-performance-collector,” and the runtime is Python 3.14. Under Additional settings, the “Custom execution role” toggle is enabled, and the execution role list is set to “redshift-performance-recommendations-role.” Annotation highlights mark the Author from scratch option, function name, runtime, custom execution role toggle, the selected role, the Save button, and the “Create function” button.

    Figure 4 – Create AWS Lambda function

  • Select Author from scratch, enter redshift-performance-collector as the name, and select Python 3.14.
  • Expand Custom settings, toggle Custom execution role, choose an existing role, select redshift-performance-recommendations-role, and choose Save.
  • On the function page, choose Upload from, .zip file, and upload build/collector.zip.
  • In Runtime settings, select Edit, and set the Handler to collector.lambda_handler.

    Lambda console for the “redshift-performance-collector” function, Code tab. The code editor shows collector.py — a Python file that runs diagnostic SQL queries against Amazon Redshift Serverless, collects CloudWatch metrics, writes telemetry to Amazon S3, and invokes the analyzer Lambda. The Runtime settings section below shows the Handler highlighted as “lambda_function.lambda_handler,” with an arrow pointing to the Edit button and the “Upload from .zip file” option highlighted.

    Figure 5 – Set AWS Lambda handler

  • Choose Configuration, Edit, set timeout to 5 minutes, and memory to 256 MB.

    Lambda console for “redshift-performance-collector,” Configuration tab with “General configuration” selected. The panel shows Memory 128 MB, Ephemeral storage 512 MB, and Timeout 0 min 3 sec, with SnapStart set to None. Annotation arrows point to the General configuration menu item and the Edit button.

    Figure 6 – Set AWS Lambda timeout and memory

  • Under Configuration, select Environment variables, and add the following keys:
    • WORKGROUP: your Amazon Redshift Serverless workgroup name.
    • NAMESPACE_NAME: the namespace the workgroup belongs to.
    • DATABASE: dev (or your target database).
    • BUCKET: the Amazon S3 bucket name you created earlier.
    • SECRET_ARN: the AWS Secrets Manager secret ARN you copied earlier.
    • ANALYZER_FN: redshift-performance-analyzer.

Package and create the analyzer

Repeat the same steps for the analyzer, using lambda/analyzer.py with a 15-minute timeout:

(cd lambda && zip -q ../build/analyzer.zip analyzer.py)

Use the Lambda console to create redshift-performance-analyzer with handler analyzer.lambda_handler, timeout 15 minutes, memory 256 MB, the same execution role, and these environment variables:

  • BUCKET: the same Amazon S3 bucket.
  • SNS_TOPIC: the SNS topic ARN.
  • MODEL_ID: us.anthropic.claude-sonnet-4-6.

The analyzer creates the Amazon Bedrock client with read_timeout=600 and max_tokens=16384 to handle large prompts and long responses. Anthropic Claude inference on a full telemetry payload typically takes 2–4 minutes.

How the signals and the prompt work

You don’t write any custom code for signal computation or prompt construction. Both computation and construction live in the repository.

The compute_signals() function in lambda/collector.py scans the telemetry for Boolean and threshold-based anti-patterns. At the table level, it looks for row skew, ghost rows, stale statistics, unsorted data, sub-optimal sort or distribution keys, and oversized VARCHAR columns. It also flags runtime and workload issues such as disk spill, small-insert bursts, high Data Definition Language (DDL) executions, and unoptimized COPY file size. Beyond that, it catches Amazon Redshift Spectrum queries that fail to prune partitions and data sharing materialized views doing full refresh. It also flags WLM configurations that lack Query Monitoring Rules (QMR), such as limits on blocks spilled to disk and query execution time. The full set of signals and thresholds is defined inline in the function. To tune a threshold or add a custom signal, edit this function and redeploy.

The build_prompt() function in lambda/analyzer.py constructs the Amazon Bedrock prompt in four sections. The first section lists the triggered signals. The second adds CloudWatch metrics, annotated with >> CORRELATION lines that pair each signal with its supporting metric. The third includes the filtered supporting data, limited to the table and query rows that triggered a signal. The fourth gives explicit instructions to return a pipe delimited text where every recommendation references specific table names, query IDs, and metric values. This structure is why the model produces targeted output rather than generic best-practice advice.

Schedule daily runs

Use the Amazon EventBridge console to trigger the collector every 24 hours.

  • Open the EventBridge console and choose Schedules under Scheduler, Create schedule.
  • Enter the name redshift-performance-daily for Schedule name, toggle Recurring schedule and Rate-based schedule.
  • Under Rate expression, enter 24 and select hours.
  • For Flexible time window, choose Off, and select Next.
    Amazon EventBridge Scheduler “Create schedule” page, Step 1: Specify schedule detail. The schedule name is “redshift-performance-daily.” Under Schedule pattern, “Recurring schedule” and “Rate-based schedule” are selected, with a rate expression of 24 hours, and the time zone set to (UTC-06:00) America/Denver. Annotation highlights mark the Schedules nav item, the recurring/rate-based selections, the rate expression, and the Next button.

    Figure 7 – Create Amazon EventBridge schedule


  • On the Select target page, choose AWS Lambda, select the redshift-performance-collector function, and choose Next.

    EventBridge Scheduler “Create schedule” page, Step 2: Select target. “Templated targets” is selected and the AWS Lambda “Invoke” target is chosen from the grid of target options. In the Invoke section, the Lambda function list is set to “redshift-performance-collector” with an empty JSON payload. Annotation highlights mark the Templated targets toggle, the AWS Lambda Invoke target, the selected function, and the Next button.

    Figure 8 – Select Amazon EventBridge schedule target

  • Accept the defaults for Settings and select Next. EventBridge automatically adds a resource-based permission on the Lambda function so the rule can invoke it.
  • Choose Create schedule.

Run it once and review the output

Invoke the collector manually to confirm the pipeline works end-to-end.

  • In the Lambda console, open the redshift-performance-collector function and choose Test. Create a test event named manual with the body {} and choose Test.

    Lambda console for “redshift-performance-collector,” Test tab. A new test event named “manual” is being configured with Invocation type set to Synchronous, event sharing set to Private, the “Hello World” template selected, and an empty {} Event JSON body. Annotation arrows point to the function in the left nav, the Synchronous option, the event name, the Event JSON field, and the Test button.

    Figure 9 – Test end-to-end workflow

  • The function completes in under a minute. Check the Monitor tab for the invocation log via the CloudWatch live logs link.
  • In the Amazon S3 console, open your bucket. Confirm that the telemetry/ prefix contains a JSON file with the current timestamp.
  • Within 2–4 minutes, the analyzer publishes a message to the SNS topic. Check the email address you subscribed for the summary with the top 10 recommendations. Confirm that the recommendations/ prefix in Amazon S3 contains the full JSON.

Each recommendation has a priority (critical, high, medium, low) and a category (query_optimization, table_design, capacity, wlm, maintenance, or ingestion). It also includes a signal_source that names the signals and CloudWatch metrics that triggered it, a plain-language explanation, a specific SQL or configuration action, and an expected impact estimate.

Email notification from AWS Notifications with the subject “Redshift performance: 3 critical, 5 high, 4 medium, 2 low (8 signals)” highlighted. The body is a plain-text “Amazon Redshift Performance Recommendations” report listing workgroup, namespace, database, analysis time, and 14 recommendations. Two critical items are shown for the game_events table: fixing extreme row-skew via DISTSTYLE ALL, and eliminating non-encoded columns with column compression, each with a category, source, explanation, SQL action, and expected impact.

Figure 10 – Sample analyzer emailed output

Best practices

  • Tune thresholds to your workload. The default thresholds in compute_signals() come from the Amazon Redshift operational review playbook. For high-velocity ingestion or small-cluster environments, consider lowering the small-insert threshold, widening the stale-statistics window, or adding custom signals for your own tables.
  • Keep the signal-to-metric correlations current. When you add a signal, also add a matching correlation in build_correlations(). The inline >> CORRELATION lines are what make the model connect an infrastructure metric to an application-level symptom.
  • Review recommendations before you act. The analyzer produces prioritized suggestions, but VACUUM, ANALYZE, and ALTER TABLE actions change table state. Read the explanation and action on each recommendation, validate the SQL against your schema, and run it during a maintenance window.

Cleaning up

To avoid ongoing charges, delete the resources you created for this solution:

  • The two AWS Lambda functions: redshift-performance-collector and redshift-performance-analyzer.
  • The Amazon EventBridge rule: redshift-performance-daily.
  • The Amazon SNS topic and its email subscription: redshift-performance-recommendations.
  • The Amazon S3 bucket, including the telemetry/ and recommendations/ objects.
  • The AWS Secrets Manager secret: redshift-performance-admin.
  • The IAM role and its inline policy: redshift-performance-recommendations-role.

Conclusion

You now have a daily performance review for Amazon Redshift Serverless that runs entirely on AWS Lambda, stores every run in Amazon S3, and delivers prioritized recommendations by email. The signal-based prompt pattern keeps the Amazon Bedrock cost low and the recommendations specific to your workload.

To learn more, see the following resources:


About the authors

Steve Phillips

Steve Phillips

Steve is a Principal Technical Account Manager and Analytics specialist at AWS in the North America region. Steve currently focuses on data warehouse architectural design, AI/ML data foundations, data lakes, data ingestion pipelines, and cloud distributed architectures.

Richard Raseley

Richard Raseley

Richard is a Senior Technical Account Manager in North America who works with Games customers. He is passionate about applying his background in automation, cloud computing, networking, and storage to help customers build AI solutions.

Building fault-tolerant multi-agent AI workflows with AWS Lambda durable functions

Post Syndicated from Satish Kamat original https://aws.amazon.com/blogs/compute/building-fault-tolerant-multi-agent-ai-workflows-with-aws-lambda-durable-functions/

Agentic AI workflows coordinate multiple agents that reason, plan, and act across multi-step processes. Each step is expensive, non-deterministic, and unpredictable in latency. Human review gates can pause execution for days. Transient failures are expected, and restarting a half-finished workflow wastes time and money. Duplicate actions, like charging a payment twice or sending the same request again, create financial and compliance risk. Until now, solving these problems meant building custom infrastructure such as state machines, queues, checkpoint stores before writing a single line of business logic.

Prior authorization is one of the most time-consuming steps in healthcare delivery. A provider must get approval from an insurer before certain treatments or medications are covered. The insurer evaluates whether the care is medically necessary, safe, and cost-effective.

Agentic AI is transforming this process. What previously took days — extracting clinical data, evaluating medical necessity, checking payer-specific criteria, and getting physician sign-off — can now be handled by AI agents that pull records, apply guidelines, and draft justification letters automatically.

This post shows how AWS Lambda durable functions can orchestrate an agentic healthcare prior authorization workflow. The pipeline coordinates multiple AI agents, a human review gate, and an external payer submission into a single fault-tolerant function. Using two key patterns — callbacks for human-in-the-loop approvals and asynchronous agent invocations, and polling for long-running external tasks — Lambda durable functions let you focus on the clinical workflow rather than building custom state machines, retry logic, and checkpoint infrastructure.

Overview of AWS Lambda durable functions

Lambda durable functions extend the standard Lambda programming model with a checkpoint and replay mechanism. You wrap your handler with the durable execution SDK, which enhances the Lambda context with durable operations such as context.step(), context.waitForCallback(), and context.waitForCondition(). These operations checkpoint progress, handle failures, and suspend execution during wait periods. If a failure occurs or the function resumes after being suspended, Lambda invokes your function again. It restores the previous state by replaying the event handler from the start and skipping over previously completed durable operations. Lambda durable functions offer additional patterns such as parallel execution, durable invocations, and saga-style compensations. Refer to the AWS Durable Execution SDK Developer Guide for the full set of capabilities.

Agentic AI workflows are a natural fit for durable functions because each agent invocation is typically expensive, slow, and prone to transient failures, which are exactly the properties that benefit from automatic checkpointing and replay. Beyond orchestrating agent steps, durable functions can pause the workflow execution for external input. You can suspend the execution until a human approval arrives, or poll an external system for completion with configurable backoff. For on-demand functions, you don’t incur compute charges while execution is suspended (see Lambda pricing for details).

The healthcare prior authorization pipeline

The prior authorization workflow orchestrator coordinates four AI agents, a human review gate, and a payer submission.

  1. Clinical extraction agent (step). Extracts relevant clinical data (diagnosis codes, procedure history, lab results) from the patient’s medical records.
  2. Medical necessity agent (step). Evaluates whether the procedure meets clinical guidelines based on the extracted data.
  3. Payer criteria agent (step). Checks the specific payer’s authorization requirements and identifies any missing documentation.
  4. Justification generation agent (step). Produces the prior authorization justification letter using the outputs of the previous three agents.
  5. Physician review (callback). The orchestrator suspends and waits for a physician to review and approve the generated justification. Because this uses waitForCallback(), the function incurs no compute charges while the physician takes minutes, hours, or days to respond.
  6. Payer submission and adjudication (polling). Once approved, the orchestrator submits the authorization request to the payer system using an idempotent step with a clientRequestToken (shown in the code below) to help prevent duplicate submissions. It then polls the payer’s adjudication status using waitForCondition() with exponential backoff, suspending between each check.

Six-stage prior authorization pipeline showing sequential agent steps, physician review callback, and payer submission with polling

Figure 2. The six-stage prior authorization pipeline, orchestrated by a single Lambda durable function.

Putting it together in code

The entire pipeline, from agent steps to human review to payer submission and polling, lives in a single function that reads top to bottom:

@durable_execution
def handler(event: dict, context: DurableContext) -> dict:
    # 1-4: Sequential agent steps (each checkpointed)
    clinical_data = context.step(extract_clinical_agent(event["patient_id"]))
    necessity = context.step(medical_necessity_agent(clinical_data))
    criteria = context.step(payer_criteria_agent(event["payer_id"], necessity))
    justification = context.step(justification_agent(clinical_data, necessity, criteria))

    # 5: Suspend until physician approves (minutes to days, zero compute cost)
    def submit_for_review(cb_id, ctx):
        send_to_review_system(cb_id, justification)

    approval = context.wait_for_callback(
        submitter=submit_for_review,
        config=WaitForCallbackConfig(timeout=Duration.from_days(7)),
        name="physician_review",
    )

    if not approval.get("approved"):
        return {"status": "REJECTED", "reason": approval.get("reason")}

    @durable_step
    def make_idempotency_key(ctx: StepContext) -> str:
        return str(uuid.uuid4())

    # 6: Submit to payer and poll for decision
    idempotency_key = context.step(make_idempotency_key(), name="idempotency-key")
    submission = context.step(submit_authorization(justification, idempotency_key))

    def check_payer_status(state, ctx):
        return {**state, "status": get_payer_status(state["submission_id"])}

    decision = context.wait_for_condition(
        check=check_payer_status,
        config=WaitForConditionConfig(
            initial_state={"submission_id": submission["id"], "status": "PENDING"},
            wait_strategy=payer_adjudication_strategy,
        ),
        name="payer_adjudication",
    )

    return {"status": decision["status"], "authorization_id": submission["id"]}

How the orchestrator handles failures

The orchestrator is designed to handle the failure modes that come up in real workflows:

  • An agent step fails. If the medical necessity agent fails after the clinical extraction agent has completed, Lambda durable function replays the handler, skips the extraction step which was already checkpointed, and retries only the failed step. This helps avoid re-incurring the time, cost, and token spend of completed steps.
  • The physician rejects the justification. The callback returns approved: false, the orchestrator returns a REJECTED status, and no payer submission occurs.
  • Payer adjudication exceeds the max attempts. waitForCondition() raises a timeout error after the configured attempt limit, which you can catch and route to a manual review queue or compensating action.
  • The submit step retries after a transient failure. Because the submission carries a clientRequestToken derived from the execution ID, retries against the payer are idempotent at the payer API level, which helps prevent duplicate authorization requests.

The callback pattern

The callback pattern allows the orchestrator to suspend execution and wait for an external signal before resuming. When the durable function reaches a context.waitForCallback(), it sends a unique callbackId to an external system and then suspends. When the external system completes its work, it calls the Lambda API with SendDurableExecutionCallbackSuccess (or SendDurableExecutionCallbackFailure) to resume the orchestrator from where it left off.

In the prior authorization pipeline, this is how the physician review step works. After the justification generation agent produces a letter, the orchestrator emits a callback ID to the clinical review system and suspends. The physician receives the draft in their review queue, reads it, and either approves or rejects it through the review UI. The UI calls the Lambda callback API with the result, and the orchestrator resumes with the approval decision.

Because the function is fully suspended, it incurs no compute charges during the review window, whether that’s 10 minutes or 3 days.

Callback flow showing the orchestrator emitting a callback ID, suspending, and resuming when the physician approves or rejects

Figure 3. The callback flow for the physician review step. The orchestrator emits a callback ID to the clinical review system and suspends. When the physician approves or rejects, the review system calls SendDurableExecutionCallbackSuccess to resume the orchestrator with the decision.

The callback pattern is appropriate when:

  • A human needs to review and approve a result (hours to days).
  • An external agent is invoked asynchronously and the orchestrator should resume when it finishes.
  • A webhook or third-party system signals completion.

The polling pattern

When an external system cannot send a callback, for example a payer API that offers no webhook support, the polling pattern provides an alternative. The orchestrator monitors the long-running task by periodically checking its status using context.waitForCondition().

# Poll the payer's adjudication API with exponential backoff
decision = context.wait_for_condition(
    check=lambda state, ctx: {**state, "status": get_payer_status(state["submission_id"])},
    config=WaitForConditionConfig(
        initial_state={"submission_id": "auth-789", "status": "PENDING"},
        wait_strategy=create_wait_strategy(WaitStrategyConfig(
            should_continue_polling=lambda state: state["status"] == "PENDING",
            max_attempts=48,
            initial_delay=Duration.from_seconds(30),
            max_delay=Duration.from_seconds(300),
            backoff_rate=2.0,
        ))
    ),
    name="payer_adjudication",
)

It runs a check function periodically as configured by a wait strategy and evaluates the result. If the task isn’t complete, suspends for a configurable delay before checking again. The function incurs no compute charges during each wait interval. Each poll result is automatically checkpointed, so on replay the orchestrator skips previously completed checks.

In the prior authorization pipeline, this is how the payer adjudication step works. Most payer APIs accept a submission and return a tracking ID, but don’t push a completion signal back. The orchestrator calls waitForCondition() with the payer’s status API, an exponential backoff strategy (30 seconds to 5 minutes), and a maximum attempt count that covers the payer’s typical adjudication window.

Lambda durable functions provide waitForCondition() with built-in support for configurable backoff strategies, maximum attempt limits, and timeouts, which can help reduce the need for separate polling infrastructure such as scheduled rules, state machines, or custom retry logic.

Polling flow showing the orchestrator checking payer status with exponential backoff until adjudication completes

Figure 4. The polling flow for the payer adjudication step

Polling is appropriate when:

  • An async job does not support callbacks.
  • An external API or system exposes only a status or Describe endpoint.
  • The orchestrator waits for a resource to become available.

Cost and operational concerns

Here are a few implications when using orchestration of agentic workflows with Lambda durable functions:

  • Retries don’t re-run completed agents. If the fourth agent fails, the first three are not re-invoked, so the organization does not pay token costs twice for the same work.
  • Idempotency tokens help prevent duplicate payer submissions. A retry that crosses the submission step reuses the clientRequestToken, which helps the payer deduplicate on their side. This is an important property when duplicate authorization requests can trigger compliance issues.
  • Replay-aware logger streamlines logging. The SDK’s logger (context.logger) is replay-aware, meaning that it automatically suppresses duplicate log lines during replay.
  • Operational visibility is consolidated. Instead of stitching together logs from a state machine, a queue, a checkpoint table, and a poller, the entire workflow is one function with one execution history. Lambda publishes durable-execution-specific Amazon CloudWatch metrics, including ApproximateRunningDurableExecutions, DurableExecutionDuration, and DurableExecutionFailed, so you can track running workflows, detect failures, and set alarms at the execution level. Lambda also publishes durable execution status change events to Amazon EventBridge (RUNNING, SUCCEEDED, FAILED, TIMED_OUT) for triggering notifications or downstream workflows, and you can enable AWS X-Ray for distributed tracing across the entire execution. For more details, see Monitoring durable functions in the Lambda developer guide.

Amazon CloudWatch metrics dashboard showing durable execution monitoring with duration and failure tracking

Using coding agents to build and test durable functions

To accelerate building agentic workflow orchestration with Lambda durable functions, you can use the Kiro power for Lambda durable functions or the Agent Plugin for AWS Serverless, which is available in any AI coding assistant tool that supports agent plugins such as Claude Code and Cursor. You can also install agent skills from the plugin individually in any AI coding assistant tool that supports agent skills. This helps your coding agents such as Kiro to:

  • Scaffold an orchestrator function from a prose description of the workflow, wiring up context.step(), wait_for_callback(), and wait_for_condition() calls based on the described stages.
  • Generate unit tests that exercise the replay behavior, including tests that inject failures at specific steps to confirm that completed checkpoints are skipped on retry.
  • Generate integration tests that simulate callback delivery and polling responses so you can validate end-to-end behavior without a full external system.

Conclusion

Agentic AI workflows can be non-deterministic, long-running, and failure-prone. Lambda durable functions can help address these challenges by adding checkpointing, replay, and suspension to the Lambda programming model, so completed work is skipped on retry and failures resume exactly where they occurred.

In this post, we walked through a healthcare prior authorization pipeline to illustrate two patterns: Callbacks for human-in-the-loop approvals and asynchronous agent invocations, and polling for monitoring long-running external tasks.

Beyond these two patterns, Lambda durable functions offer additional capabilities for building resilient workflows such as parallel execution, child contexts for isolated execution context for grouping operations, and saga-style compensations. Refer to the Lambda durable functions Developer Guide for the full set of capabilities. For pricing of on-demand and provisioned-concurrency functions, see the Lambda pricing page.

Get started with Lambda durable functions with examples from Serverlessland and install the Agent Plugin for AWS Serverless.

Build reliable voice analytics workflows with AWS Lambda durable functions and Amazon Bedrock

Post Syndicated from Mehdi Amrane original https://aws.amazon.com/blogs/compute/build-reliable-voice-analytics-workflows-with-aws-lambda-durable-functions-and-amazon-bedrock/

Contact centers handle millions of voice interactions monthly, but transforming raw call recordings into actionable insights remains a manual and fragile process. With voice analytics workflows, you can decrease the average handle time of a voice call from minutes to seconds and increase the efficiency and productivity of your support agents.

Today, these workflows often require custom code to handle non-functional requirements such as retry logic, state management and failure handling across multiple services. In addition, as the selection/determination of insights is derived from specific business objectives, it often needs to be customized for each organization.

In this post, we show a solution using AWS Lambda durable functions to create the following insights: summarization, sentiment analytics and key topics. AWS Lambda durable functions is a capability of AWS Lambda, that simplifies building multi-step applications and AI workflows. It lets you write sequential code with automatic checkpointing, built-in retries, and simplified error handling, so you can focus on the business logic rather than managing the orchestration.

The solution also simplifies the visualization of the conversation transcriptions and insights, with a web application.

Solution overview

In this post, we provide an operational overview of the solution, and then describe how to set it up with the following services:

The solution architecture is illustrated in the following diagram:

Architecture diagram showing the solution components and data flow for voice analytics with AWS Lambda durable functions and Amazon Bedrock

Step 1 (Option 1): Transcription segments are sent by an external system. The segments are stored in a stream (Amazon Kinesis Streams).

Step 1 (Option 2): Voice calls are sent by an external system to the Contact Lens Connector in AWS. The voice calls are then transcribed using Amazon Connect Contact Lens, to generate transcriptions and send these transcriptions to the stream.

  • Step 1a: The external system sends a copy of the voice call to a Contact Lens Connector.
  • Step 1b: The Contact Lens Connector routes the voice call to Amazon Connect Contact Lens.
  • Step 1c: Amazon Connect Contact Lens generates transcriptions from a voice call.
  • Step 1d: The transcription segments are stored in a stream (Amazon Kinesis Streams).

Step 2: A transcription processor function (AWS Lambda function) consumes transcription segments from the stream.

Step 3: The transcription processor function (AWS Lambda function) stores transcription segments in a transcription table in Amazon DynamoDB.

Step 4: A durable function (AWS Lambda Durable function) is triggered when new transcription segments are stored in the transcription table (the trigger is implemented using Amazon DynamoDB Streams). It orchestrates the processing of transcriptions in 5 steps.

  • Step 4a: The durable function fetches the segments received for a given transcription. If all the segments of voice call are available, the processing continues to Step 4b. Otherwise, the Lambda function is stopped (since the transcription is not complete yet).
  • Step 4b: The durable function summarizes the voice transcription using Amazon Bedrock.
  • Step 4c: The durable function generates sentiment analytics for the voice transcription using Amazon Bedrock.
  • Step 4d: The durable function extracts key topics from the voice transcription using Amazon Bedrock.
  • Step 4e: The durable function stores the conversational insights in an analytics table in Amazon DynamoDB.

Step 5 and 6: The user accesses the web application and authenticates.

Step 7: Amazon Cognito validates the authentication details.

Step 8: Once the user is logged in, the web application sends a request to an API (Amazon API Gateway) to fetch the voice transcriptions and conversational insights.

Step 9: The API calls a Lambda authorizer to confirm that the user is authorized to retrieve the voice transcriptions and conversational insights.

Step 10: The request is sent from the API to a retriever function (AWS Lambda function to retrieve transcriptions from the transcription table and conversational insights from the analytics table).

Step 11: The Lambda function retrieves transcriptions from the transcription table and conversational insights from the analytics table.

After Step 11, the user can now consult the transcriptions and conversational insights from the web application.

Prerequisites

  • An AWS account.
  • A Unix based device (or Windows device with WSL setup to run bash scripts) with access to your AWS account with the following tools/libraries installed:
    • Node.js and npm installed.
    • Python 3.12 installed.
    • Docker (for front-end containerization).
    • AWS Command Line Interface (AWS CLI) configured with appropriate permissions.
    • CDK installed.
  • Clone the GitHub repository:
    git clone https://github.com/aws-samples/sample-sca-with-lambda-durable-and-bedrock.git

Set up network and backend infrastructure

In this section, we setup the networking and backend resources of the solution.

Navigate inside the repository and complete the following steps to create these resources:

  1. Install dependencies and build project:
    npm install
    npm run build
    cdk bootstrap

  2. Create networking infrastructure resources (Amazon Virtual Private Cloud (Amazon VPC), subnets, IAM roles, security groups and VPC endpoints):
    cdk deploy ScaNetworkStack

  3. Create backend resources (Amazon Kinesis Data Streams stream, Amazon DynamoDB tables, AWS Lambda functions, Amazon API Gateway, Amazon Cognito):
    cdk deploy ScaBackendStack

Create the web application

In this section, we create the web application of the solution.

Complete the following steps to create the web application:

  1. Create an Amazon Elastic Container Registry (Amazon ECR) repository to host the container image of the web application:
    cdk deploy ScaEcrStack

  2. Build and deploy container image in the Amazon ECR repository:
    chmod +x scripts/deploy-container.sh
    bash ./scripts/deploy-container.sh us-west-2

    Note: Replace us-west-2 with your deployment region.

  3. Deploy the web application:
    cdk deploy ScaWebAppStack

  4. Deploy CloudFront Access stack (optional). This stack adds public subnets, an internet gateway, and an Amazon CloudFront distribution.Important note: This stack allows access to the web application from a public endpoint using an Amazon CloudFront distribution. You can use this stack if you currently cannot access a web application behind a private ALB with an existing private connection (virtual private network (VPN), AWS Direct Connect, etc.).
    cdk deploy ScaCloudFrontAccessStack -c enableCloudFrontAccess=true

The web application is now available for testing.

If your web application is private, the application is deployed behind a private ALB. Access it from within the VPC using the ALB DNS name:

aws cloudformation describe-stacks --stack-name ScaWebAppStack --query 'Stacks[0].Outputs[?OutputKey==`AlbDnsName`].OutputValue' --output text

If your web application is public, the application is deployed behind an Amazon CloudFront distribution. You can access it using the CloudFront distribution URL:

aws cloudformation describe-stacks --stack-name ScaCloudFrontAccessStack --query 'Stacks[0].Outputs[?OutputKey==`CloudFrontUrl`].OutputValue' --output text

Configure the Amazon Cognito user pool

In this section, we create a user in our Amazon Cognito user pool. This user will log in to our web application.

Run the script setup-test-user.sh to create the user (make sure to provide your email address):

chmod +x scripts/setup-test-user.sh
./scripts/setup-test-user.sh [email protected]

Note: Replace [email protected] with your email address.

After you create the user, you should receive an email with a temporary password in this format: “Your username is #your-email-address# and temporary password is #temporary-password#.”

Keep note of these login details (email address and temporary password) to use later when testing the web application.

Test the solution

In this section, we test the solution by ingesting a transcription in the stream (Amazon Kinesis Data Streams) and visualize the results in the web application.

  1. Run the script ingest-transcriptions.sh to ingest a sample transcription in the stream:
    chmod +x scripts/ingest-transcriptions.sh
    ./scripts/ingest-transcriptions.sh

  2. Open the URL of the web application in your web browser (either CloudFront distribution URL or ALB DNS name as mentioned in previous section).
  3. Enter your login information (your email and the temporary password you received earlier while configuring the user pool in Amazon Cognito) and choose Sign in.
  4. When prompted, enter a new password and choose Change Password.
  5. You should now be able to see a web interface with a transcription as illustrated in the following screenshot:Web interface displaying a list of voice transcriptions
  6. Select a transcription to visualize the conversational insights as shown in the following screenshot.Conversational insights detail view showing summary, sentiment, and key topics for a selected transcription

If you want to explore an alternative option by placing a voice call using Amazon Connect (with Amazon Connect Contact Lens to generate the transcriptions):

Clean up

To make sure that no additional cost is incurred, remove the resources provisioned in your account. Make sure you’re in the correct AWS account before deleting the resources.

Important note: You should exercise caution when performing the preceding steps. Make sure you are deleting the resources in the correct AWS account.

You can navigate to the AWS CloudFormation console to delete the CloudFormation stacks associated to the resources provisioned.

You can also destroy the stacks using cdk destroy in reverse dependency order:

  1. If you deployed the optional CloudFront access stack:
    cdk destroy ScaCloudFrontAccessStack -c enableCloudFrontAccess=true

  2. If you deployed the optional Connect integration stack:
    cdk destroy ScaConnectStack -c enableConnect=true

  3. To destroy the core stacks:
    cdk destroy ScaWebAppStack
    cdk destroy ScaEcrStack
    cdk destroy ScaBackendStack
    cdk destroy ScaNetworkStack

Conclusion

In this post, we walked through a solution to create a web application to visualize voice transcriptions and related conversational insights. First, we created network and backend resources. Then we created the web application. We also configured a user pool to grant a user access to the web application. Finally, we tested solution by ingesting transcriptions then visualize them in the web application.

For further information, consult the documentation of the following services: Amazon Bedrock, AWS Lambda durable functions, Amazon ECS, Amazon API Gateway, AWS Lambda, Amazon Kinesis Streams, Amazon DynamoDB and Amazon Cognito.

To dive deeper into this solution, a GitHub repository is available at this location.

Modernizing Lambda + S3 workloads with Amazon S3 Files

Post Syndicated from Sahithi Ginjupalli original https://aws.amazon.com/blogs/compute/modernizing-lambda-s3-workloads-with-amazon-s3-files/

Learn how Amazon S3 Files simplifies Lambda functions by eliminating transfer code and /tmp constraints. See three modernization patterns with code examples for image processing, ETL pipelines, and multi-agent AI workloads.

AWS Lambda functions that interact with Amazon Simple Storage Service (Amazon S3) typically follow a familiar pattern: download an object to /tmp, process it locally, and upload the result back to S3. This pattern is well-understood and reliable, but it requires you to write code for managing transfers, monitoring /tmp capacity, and cleaning up ephemeral storage alongside your actual processing logic.

Amazon S3 Files changes this by letting your Lambda function mount an S3 bucket as a file system. Your function reads and writes files at a local mount path (such as /mnt/data), and the file system handles synchronization with S3 automatically. The transfer and storage management code goes away, and what remains is your processing logic working directly with files.

In this post, we walk through three common Lambda + S3 workloads and show how to modernize each one by using S3 Files. You will see how the code gets shorter, the /tmp size constraint disappears, and the developer experience improves.

Walkthrough

Prerequisites

Before you begin, make sure you have:

  • An AWS account with permissions to create Lambda functions, S3 file systems, and VPC resources.
  • An existing VPC with private subnets and appropriate security groups.

Getting started

To integrate a Lambda function with S3 Files, you can follow these three steps:

  1. Create an S3 file system for your bucket. You can do this through the S3 console, AWS Command Line Interface (AWS CLI), or AWS CloudFormation. This single operation creates the file system, mount targets in your Amazon Virtual Private Cloud (Amazon VPC), and an access point.
  2. Add the file system configuration to your Lambda function. Specify the access point ARN and local mount path (for example, /mnt/data). Your function must be in a VPC with access to the mount target. For optimal throughput on large files, configure your function with 512 MB or more of memory to enable direct reads from S3.
  3. If you are modernizing your existing Lambda function’s code, replace boto3 transfer code with file paths. Change s3.download_file(bucket, key, '/tmp/file') to open('/mnt/data/' + key) and remove upload and cleanup logic.

Your function’s execution role needs s3files:ClientMount and s3files:ClientWrite permissions (included in the AmazonS3FilesClientReadWriteAccess managed policy). For direct S3 reads on large files, also add s3:GetObject and s3:GetObjectVersion.

Pattern 1: Multi-agent shared workspace

Agentic AI workloads, where multiple autonomous agents collaborate on a task, require shared mutable state. Agents need to read each other’s outputs, write intermediate artifacts, and coordinate without tight coupling. With Lambda today, this typically means serializing state to S3 objects or Amazon DynamoDB between every step, adding latency and code for each handoff.

S3 Files gives multiple Lambda functions a shared file system. Agents communicate through the file system itself, with no S3 API calls and no serialization overhead.

Example: Collaborative research agents

Three Lambda functions mount the same S3 bucket at /mnt/workspace. An orchestrator prepares the task, research agents work in parallel, and a synthesis agent combines their findings:

import os
import json

WORKSPACE = "/mnt/workspace"

# --- Orchestrator Agent ---
def orchestrator_handler(event, context):
    session_id = event["session_id"]
    session_dir = f"{WORKSPACE}/sessions/{session_id}"

    os.makedirs(f"{session_dir}/research", exist_ok=True)
    os.makedirs(f"{session_dir}/output", exist_ok=True)

    # Write task assignments directly to shared workspace
    with open(f"{session_dir}/manifest.json", "w") as f:
        json.dump({
            "query": event["research_query"],
            "agents": ["market_analysis", "technical_review", "competitor_scan"],
            "status": "in_progress"
        }, f)

    return {"session_dir": session_dir}


# --- Research Agent (one of many, running in parallel) ---
def research_agent_handler(event, context):
    session_dir = event["session_dir"]
    agent_name = event["agent_name"]

    # Read task from shared workspace (no S3 GET call)
    manifest = json.load(open(f"{session_dir}/manifest.json"))

    # Perform research (invoke Amazon Bedrock, search, etc.)
    # TODO: Implement perform_research() for your use case
    findings = perform_research(manifest["query"], agent_name)

    # Write results to shared workspace (no S3 PUT call)
    with open(f"{session_dir}/research/{agent_name}.json", "w") as f:
        json.dump(findings, f, indent=2)

    return {"status": "complete", "agent": agent_name}


# --- Synthesis Agent ---
def synthesis_handler(event, context):
    session_dir = event["session_dir"]

    # Read all research outputs from shared directory
    all_findings = {}
    for f in os.listdir(f"{session_dir}/research"):
        with open(f"{session_dir}/research/{f}") as fh:
            all_findings[f.replace(".json", "")] = json.load(fh)

    # Synthesize and write final report
    # TODO: Implement synthesize_findings() for your use case
    report = synthesize_findings(all_findings)
    with open(f"{session_dir}/output/report.md", "w") as f:
        f.write(report)

    return {"report_path": f"{session_dir}/output/report.md"}

In the traditional approach, each agent would need to call s3.get_object() to read the manifest, s3.put_object() to write findings, and the synthesis agent would need to call s3.list_objects() then s3.get_object() for each result. That’s eight or more S3 API calls per workflow run replaced by file I/O.

What the shared workspace pattern gives you:

  • Agents discover each other’s outputs by listing a directory (no coordination logic needed).
  • Sessions, agents, and outputs map to directories, not flat object key conventions.
  • Close-to-open consistency means that when an agent closes a file after writing, the next agent to open it sees the complete content.
  • No need to marshal state into S3 PutObject calls between steps.

Pattern 2: Image thumbnail generation

The S3 thumbnail generator is a common Lambda + S3 pattern. An image is uploaded to S3, a Lambda function is triggered, it downloads the image, resizes it with Pillow, and uploads the thumbnail to a destination bucket.

The traditional approach

import boto3
import os
import uuid
from urllib.parse import unquote_plus
from PIL import Image

s3_client = boto3.client('s3')

def resize_image(image_path, resized_path):
    with Image.open(image_path) as image:
        image.thumbnail(tuple(x / 2 for x in image.size))
        image.save(resized_path)

def handler(event, context):
    for record in event['Records']:
        bucket = record['s3']['bucket']['name']
        key = unquote_plus(record['s3']['object']['key'])
        tmpkey = key.replace('/', '')
        download_path = '/tmp/{}{}'.format(uuid.uuid4(), tmpkey)
        upload_path = '/tmp/resized-{}'.format(tmpkey)

        s3_client.download_file(bucket, key, download_path)
        resize_image(download_path, upload_path)
        s3_client.upload_file(
            upload_path, '{}-resized'.format(bucket), 'resized-{}'.format(key)
        )

What this approach requires you to manage beyond the core resize logic:

  • Transfer orchestration: Downloading the source, uploading the result, and handling partial transfer failures.
  • Storage capacity: Both the source and resized image must fit in /tmp simultaneously.
  • Ephemeral storage cleanup: If the function fails mid-execution or is reused across invocations, orphaned files can accumulate in /tmp.
  • Redundant downloads: If the same image triggers a retry, it must be downloaded again.

With the file system approach

import os
from urllib.parse import unquote_plus
from PIL import Image

MOUNT = "/mnt/images"

def resize_image(image_path, resized_path):
    with Image.open(image_path) as image:
        image.thumbnail(tuple(x / 2 for x in image.size))
        image.save(resized_path)

def handler(event, context):
    for record in event['Records']:
        key = unquote_plus(record['s3']['object']['key'])
        input_path = f"{MOUNT}/source/{key}"
        output_path = f"{MOUNT}/resized/resized-{os.path.basename(key)}"

        os.makedirs(os.path.dirname(output_path), exist_ok=True)
        resize_image(input_path, output_path)

What changed

The function moves from a download-process-upload pipeline to direct file I/O. No boto3 client, no /tmp management, no upload step. The resize_image function is unchanged because it always worked with file paths. The difference is that those paths now point to a mounted S3 file system instead of ephemeral local storage.

You still handle errors in your processing logic (for example, invalid image formats). What you no longer need to handle are transfer-specific failure modes like partial downloads, failed uploads, or /tmp capacity checks.

Metric Traditional S3 Files
Lines of code (non-blank) 22 15
S3 API calls per invocation 2 (GET + PUT) 0
Max image size Source + output files share /tmp No /tmp constraint
boto3 dependency Required Not needed

Pattern 3: CSV-to-Parquet ETL pipeline

Another commonly used serverless ETL pattern is an S3 event triggers a Lambda function when CSV files land in a bucket. The function downloads the CSV, transforms it to Parquet by using pandas and pyarrow, and uploads the result.

The traditional approach

import boto3
import pandas as pd
import os

s3 = boto3.client("s3")
BUCKET = "data-pipeline-bucket"

def handler(event, context):
    key = event["Records"][0]["s3"]["object"]["key"]
    filename = os.path.basename(key)
    local_input = f"/tmp/{filename}"
    local_output = f"/tmp/{filename.replace('.csv', '.parquet')}"

    try:
        # Download from S3
        s3.download_file(BUCKET, key, local_input)

        # Check /tmp space (10 GB limit)
        tmp_usage = sum(
            os.path.getsize(f"/tmp/{f}")
            for f in os.listdir("/tmp") if os.path.isfile(f"/tmp/{f}")
        )
        if tmp_usage > 9 * 1024**3:  # 9 GB safety margin
            raise RuntimeError("Approaching /tmp storage limit")

        # Transform
        df = pd.read_csv(local_input)
        df["processed_at"] = pd.Timestamp.now()
        df.to_parquet(local_output, engine="pyarrow", compression="snappy")

        # Upload result back to S3
        output_key = key.replace("raw/", "processed/").replace(".csv", ".parquet")
        s3.upload_file(local_output, BUCKET, output_key)

        return {"status": "success", "output_key": output_key}

    finally:
        # Clean up /tmp
        for f in [local_input, local_output]:
            if os.path.exists(f):
                os.remove(f)

What this approach requires you to manage beyond the core transform logic:

  • Storage capacity: Source and output files share /tmp, limiting practical file size.
  • Cold start cost: Initializing the boto3 client adds startup latency.
  • Transfer failure modes: Partial downloads, failed uploads, and orphaned /tmp files need their own handling.
  • Redundant downloads: Retries or reprocessing require downloading the same file again.

With the file system approach

import pandas as pd
import os

MOUNT = "/mnt/data"

def handler(event, context):
    key = event["Records"][0]["s3"]["object"]["key"]
    input_path = f"{MOUNT}/{key}"
    output_path = f"{MOUNT}/{key.replace('raw/', 'processed/').replace('.csv', '.parquet')}"

    # Ensure output directory exists
    os.makedirs(os.path.dirname(output_path), exist_ok=True)

    # Transform: direct file access, no download/upload
    df = pd.read_csv(input_path)
    df["processed_at"] = pd.Timestamp.now()
    df.to_parquet(output_path, engine="pyarrow", compression="snappy")

    return {"status": "success", "output_path": output_path}

What changed

With this change, a developer reading this code sees only the transform logic (read CSV, add column, write Parquet). The storage mechanics are handled by the file system.

Metric Traditional S3 Files
Lines of code (non-blank) 33 14
S3 API calls per invocation 2 (GET + PUT) 0
Max file size Source + output share /tmp No /tmp constraint
Cleanup logic required Yes No
/tmp space monitoring Yes No

Choosing the right approach: file system mounts vs. traditional access

Use case Recommendation
Lambda reads/writes files from S3 S3 Files (eliminates transfer boilerplate)
Multiple functions share data S3 Files (shared mount replaces API coordination)
Files > 10 GB S3 Files (no /tmp size constraint)
Event-driven processing (trigger on upload) S3 Files (S3 event triggers still work, function reads from mount)
Direct S3 API features (presigned URLs, S3 Select, multipart upload) Traditional (these require the S3 API)
Functions outside a VPC Traditional (S3 Files requires VPC connectivity)

Cleaning up

If you created resources while following along with this post, delete them to avoid incurring future costs. Start by removing the file system configuration from your Lambda function settings. Next, remove the S3 file system, which also deletes its associated mount targets and access points. Then delete the S3 buckets used for source and output data, along with the Lambda functions created for the examples. Finally, remove the IAM roles and policies created for Lambda execution or, if you added the S3 Files permissions (s3files:ClientMount, s3files:ClientWrite, s3:GetObject, s3:GetObjectVersion) to an existing role, remove these permissions. Additionally, If you created a new VPC for this tutorial, delete the VPC, which will also remove the associated private subnets, security groups, and route tables. If you used an existing VPC, remove the security groups and subnets created for this testing.

Warning: Deletion of an S3 bucket and its contents permanently deletes all objects in the buckets and cannot be undone. Make sure you have backed up any data you need to retain before proceeding.

Conclusion

In this post, we demonstrated how to modernize three common Lambda + S3 workloads by using Amazon S3 Files. Across image thumbnail generation, ETL pipelines, and multi-agent AI workloads, the migration follows the same principle: replace S3 API transfer logic with native file I/O and let the file system handle synchronization.

The improvements are consistent:

  • Less code: Transfer and cleanup logic goes away, leaving only your processing logic.
  • No /tmp size constraint: Process large files without local storage limits.
  • Zero S3 API calls for data access: Reads and writes go through the file system mount.
  • Fewer failure modes to handle: Transfer-specific issues (partial downloads, failed uploads, orphaned temp files) no longer apply.

For teams running Lambda + S3 workloads today, S3 Files isn’t a new architecture to learn. It’s transfer code you can remove. To learn more, see the S3 Files section in the Lambda documentation. To track upcoming features on the AWS Lambda roadmap, you can refer to the AWS Lambda roadmap.

Getting your SMS short code production-ready with AWS End User Messaging

Post Syndicated from Harshvardhan Chunawala original https://aws.amazon.com/blogs/messaging-and-targeting/getting-your-sms-short-code-production-ready-with-aws-end-user-messaging/

Getting your Short Message Service (SMS) short code production-ready requires you to configure the Amazon Web Services (AWS) infrastructure that controls how your messages are sent, monitored, and protected. You have provisioned your short code, and it is active on carrier networks. In this post, we walk through that setup using AWS End User Messaging SMS, covering 12 configuration steps from compliance through phased traffic migration. Total estimated time is 2 to 4 hours of configuration plus 1 to 3 business days for limit increase approvals.mess

The guide to SMS short codes with AWS End User Messaging covers the application and registration process up through provisioning. This post picks up from that point and provides an operational readiness walkthrough that takes you from “Active” status to confidently sending your first production message, including a final validation step to confirm readiness.

The following diagram shows the end-to-end message flow and event routing architecture covered in this walkthrough.

End-to-end SMS short code architecture showing message flow from sender through AWS End User Messaging SMS to carriers and recipient handsets, with event routing to Amazon CloudWatch, Amazon Simple Notification Service (Amazon SNS), and Amazon Data Firehose destinations

Prerequisites

You need the following to follow along with this walkthrough:

  1. An AWS account with access to the AWS End User Messaging SMS console.
  2. A short code with Active status in the AWS Management Console (carrier provisioning finished).
  3. Permissions to create AWS Identity and Access Management (IAM) roles, Amazon CloudWatch Log Groups, and Amazon Simple Notification Service (Amazon SNS) topics.
  4. AWS Command Line Interface (AWS CLI) v2 or an AWS SDK installed and configured.
  5. Your approved registration documentation, including the service name, keyword responses, and message templates submitted to carriers.

Step 1: Verify your short code is active and delivering

Navigate to the AWS End User Messaging SMS console, choose Phone numbers, and locate your provisioned short code. Confirm that the status shows Active, then send a test message to a phone number you control using the SendTextMessage API or the console test feature. Verify delivery on your handset.

Carrier-side activation can take up to 24 to 48 hours to fully propagate across all networks after provisioning finishes. If the console shows Active but your test message does not arrive, submit a support case so the team can verify propagation status with the carrier.

You can also verify using the AWS CLI:

aws pinpoint-sms-voice-v2 send-text-message \
    --destination-phone-number "+15555550100" \
    --origination-identity "12345" \
    --message-body "Test message from short code" \
    --message-type TRANSACTIONAL \
    --configuration-set-name "prod-otp-shortcode"
# Replace +15555550100 with your test phone number, 12345 with your short
# code, and prod-otp-shortcode with your configuration set name from Step 3.

Step 2: Configure keywords and verify message compliance

US carriers require every short code to respond to HELP and STOP keywords. You defined these during your registration, and this step confirms they are configured correctly in your account.

In the SMS console, choose Phone numbers, select your short code, and choose the Keywords tab. Verify that STOP returns the opt-out response you submitted during registration, and that HELP returns your support contact response (which must include a phone number or email). Add any custom keywords your use case requires, such as YES for double opt-in confirmation flows. You can manage keywords programmatically using the PutKeyword API.

To add or update a keyword programmatically:

aws pinpoint-sms-voice-v2 put-keyword \
    --origination-identity "12345" \
    --keyword "YES" \
    --keyword-message "You have confirmed your subscription to Acme Health Alerts. Msg&data rates may apply. Reply STOP to opt out." \
    --keyword-action AUTOMATIC_RESPONSE
# Replace 12345 with your short code, YES with your custom keyword, and the
# keyword-message text with your approved response.

To verify your current keyword configuration:

aws pinpoint-sms-voice-v2 describe-keywords \
    --origination-identity "12345"
# Replace 12345 with your short code.

Beyond keyword configuration, carrier compliance does not end at registration approval. The content you send in production must stay aligned with what carriers reviewed and approved. Here is what to keep consistent.

Use the exact brand or program name from your approved registration across all keyword responses, confirmation messages, and outbound templates. If carriers approved your registration under “Acme Health Alerts,” every message your short code sends should reference that name. Mixing variations creates inconsistencies that auditors flag during reviews. For example, do not use the company name in one message and the product name in another.

Your HELP, STOP, and confirmation responses must match the templates submitted during registration. Do not add or remove opt-out language, change frequency disclosures, or alter customer care contact details post-approval without updating the registration through a support case. If your organization operates multiple domains, use the domain documented in the registration. For example, you might have one domain for the application and another for marketing. Carrier reviewers cross-reference message content, opt-in screenshots, and privacy policy URLs with what was submitted.

Humans conduct carrier reviews, and message content that is concise and limited to the essentials is reviewed consistently. All messages must remain under 160 characters.

Step 3: Create a configuration set with event destinations

A configuration set controls where your SMS delivery events are streamed and which event types are captured. Without one, you are limited to the basic events that AWS End User Messaging SMS sends to Amazon EventBridge by default. These default events omit recipient details and full carrier response context.

Create a configuration set with a descriptive name such as prod-otp-shortcode or marketing-sc-us. Then create at least one event destination. The three main options are Amazon CloudWatch Logs (for operational monitoring and alarming), Amazon SNS (for real-time event fanout to downstream systems), and Amazon Data Firehose (for durable archival and analytics).

Amazon Data Firehose typically delivers to an Amazon Simple Storage Service (Amazon S3) bucket, where you can query delivery history using Amazon Athena for compliance audits or delivery pattern analysis.

# Create the configuration set
aws pinpoint-sms-voice-v2 create-configuration-set \
    --configuration-set-name "prod-otp-shortcode"

# Add a CloudWatch Logs event destination
aws pinpoint-sms-voice-v2 create-event-destination \
    --configuration-set-name "prod-otp-shortcode" \
    --event-destination-name "otp-delivery-logs" \
    --matching-event-types TEXT_DELIVERED TEXT_FAILED TEXT_QUEUED TEXT_CARRIER_UNREACHABLE TEXT_TTL_EXPIRED \
    --cloud-watch-logs-destination '{
        "IamRoleArn": "arn:aws:iam::123456789012:role/SMSEventsToCloudWatch",
        "LogGroupArn": "arn:aws:logs:us-east-1:123456789012:log-group:/aws/sms/prod-otp-shortcode"
    }'
# Replace prod-otp-shortcode with your configuration set name, otp-delivery-logs
# with a descriptive destination name, and the ARN values with your IAM role ARN
# (must have logs:PutLogEvents permission) and CloudWatch Log Group ARN.

Important: When sending messages with SendTextMessage, always specify your ConfigurationSetName parameter so events route to the appropriate destination.

Required event types

Event type Description
TEXT_DELIVERED Message successfully delivered to recipient handset.
TEXT_FAILED Message delivery failed.
TEXT_QUEUED Message accepted and queued for delivery.
TEXT_CARRIER_UNREACHABLE Carrier network unreachable.
TEXT_TTL_EXPIRED Message expired before delivery.

For a detailed walkthrough of configuration sets including multi-tenant architectures, see How to send SMS using configuration sets with AWS End User Messaging.

Step 4: Create a phone pool and associate your short code

A pool is a logical container that groups origination identities and controls routing behavior. Creating one gives you deterministic control over which number sends your messages and how opt-outs are enforced.

# Create the pool
aws pinpoint-sms-voice-v2 create-pool \
    --origination-identity "12345" \
    --iso-country-code "US" \
    --message-type TRANSACTIONAL

# Disable shared routes so only your short code is used
aws pinpoint-sms-voice-v2 update-pool \
    --pool-id "pool-1234567890abcdef0" \
    --shared-routes-enabled false
# Replace 12345 with your short code, US with your destination country code,
# and pool-1234567890abcdef0 with the Pool ID returned by create-pool.

Configuration parameters

Parameter Recommended value Rationale
Pool name us-otp-pool Descriptive, environment-prefixed.
SharedRoutesEnabled False Prevents fallback to shared routes; only your short code is used.
Opt-out list Associate one Manages opt-out state per use case.
IsoCountryCode US Restricts to destination country your short code serves.

If you operate multiple use cases on separate short codes, create a dedicated pool for each. For example, use one short code for one-time password (OTP) traffic and another for transactional notifications. This isolation means a recipient opting out of marketing messages does not lose access to authentication codes.

Step 5: Request your throughput increase

Short codes start at a default of 100 messages per second (MPS). If your production volume will exceed this, request an increase before your launch date rather than after traffic is flowing.

Create a case in the AWS Support Center, choose Service limit increase, then choose End User Messaging SMS. Provide your short code phone number, requested MPS, use case description, and expected peak volume. Allow 1 to 3 business days for processing.

To estimate your required MPS:

Required MPS = (Peak hourly volume / 3,600) x 2

Short codes support scaling to thousands of MPS, so start with a value that covers your expected peak and request further increases as traffic grows.

Step 6: Request a spending limit increase

AWS accounts have a default monthly SMS spending limit. To keep delivery uninterrupted at your expected volume, request an increase that accommodates your projected monthly spend before you begin sending.

Create a support case under Service limit increase > End User Messaging SMS > Account Spend Threshold. Provide your estimated monthly spend, use case description, and website URL.

For details, see Requesting increases to your monthly SMS spending quota.

Step 7: Restrict destination countries

If your short code serves a single country (US-only, for example), restrict sending to that country. This protects your account from artificially inflated traffic (SMS pumping). In pumping attacks, messages are routed to international premium-rate numbers, generating significant charges.

In the SMS console, navigate to Account settings, then choose Countries and keep only the countries you intend to send to. The pool-level IsoCountryCode restriction from Step 4 provides an additional enforcement layer at the sending path. Combining account-level country restrictions with pool-level country codes gives you two independent controls that both must be satisfied before a message is sent internationally.

For a detailed walkthrough on SMS fraud prevention controls, see Defending against SMS pumping: new AWS features to help combat artificially inflated traffic.

Step 8: Set up monitoring and alarms

With event destinations configured in Step 3, build proactive alerting that surfaces delivery trends before they affect your end users.

Alarm Metric / Source Threshold
Delivery success rate CloudWatch SMS metrics Alert when below 95%.
Spend threshold CloudWatch billing metric Alert at 80% of monthly limit.
Delivery failures Amazon EventBridge rule on TEXT_FAILED Route to Amazon SNS topic or AWS Lambda.
Carrier unreachable Amazon EventBridge rule on TEXT_CARRIER_UNREACHABLE Route to Amazon SNS topic or AWS Lambda.

Build a CloudWatch dashboard showing messages sent per minute, success versus failure breakdown, and spend accumulation over time.

You can also configure Amazon EventBridge to notify you of registration status changes. AWS End User Messaging SMS publishes events for statuses including REQUIRES_UPDATES, REVIEWING, and PROVISIONING, which is useful if a carrier requests changes during a proactive audit after your short code is already active.

For metric details, see Monitoring SMS activity with Amazon CloudWatch.

Step 9: Track OTP verification success (if applicable)

If your short code delivers OTP or two-factor authentication (2FA) codes, track end-to-end verification success in addition to carrier delivery receipts. A “delivered” status at the carrier level does not confirm the end user received and entered the code.

Tracking verification rates gives you insight into latency patterns when codes expire before arrival, geographic delivery trends, and opportunities to improve conversion. Some use cases involve asynchronous processing where several minutes of computation occur before the SMS is sent. For these, measure the full round-trip from the triggering action to message delivery. This separates application-side latency from carrier-side delivery latency.

For implementation guidance, see Track OTP success with AWS End User Messaging SMS feedback.

Step 10: Set up cost visibility

SMS costs include AWS charges plus per-message carrier surcharges. Setting up cost visibility from day one lets you track spend trends, catch anomalies early, and optimize over time.

Start by activating AWS Cost Explorer and creating a cost allocation tag for your SMS workload. Then configure an AWS Budget with threshold alerts. For example, you might notify at 80% of projected monthly spend. This gives you advance warning of unexpected cost increases, whether from traffic spikes, retry loops, or blocked-country leakage.

Step 11: Plan your traffic migration

A phased rollout validates delivery performance at each stage before you increase volume.

Start with a canary phase (Day 1 to 3) where you route 5 to 10% of traffic to the short code and monitor delivery rates, latency, and event logs. Move to a ramp phase (Day 3 to 7) at 50%, validating throughput and carrier-level delivery across your recipient base. Finish the full migration (Day 7+) at 100%. Decommission your previous origination identity only after confirming stability for at least 48 hours.

Step 12: Validate production readiness and send

Before declaring your short code production-ready, run through the following validation checks:

  1. Confirm your CloudWatch dashboard shows events flowing for TEXT_DELIVERED and TEXT_FAILED (from Step 3).
  2. Send a test message that triggers your STOP keyword. Verify the correct opt-out response is returned and the phone number appears in your opt-out list.
  3. Send a test message that triggers your HELP keyword. Verify the response matches your approved registration.
  4. Check your MPS quota in the support case response (from Step 5). Confirm it matches or exceeds your calculated peak.
  5. Review your country restrictions (from Step 7). Attempt to send a message to a blocked country and confirm it is rejected.
  6. Verify your CloudWatch alarm fires by temporarily lowering the threshold, or by checking that the alarm state is not INSUFFICIENT_DATA.

After all six checks pass, you are ready to begin your phased migration (Step 11) and scale to full production traffic. At this point, your short code is configured, monitored, compliant, and protected.

Automate with a validation script

You can use an AI coding assistant such as Kiro to generate a validation script tailored to your environment. Try a prompt like: “Write a boto3 script that validates my SMS short code is production-ready by checking Active status, HELP/STOP keywords, configuration set existence, and pool association using the pinpoint-sms-voice-v2 client.”

Refine the prompt with specifics from the following reference implementation, such as exact API names, filter parameters, and output format, to match your requirements.

The following script is an example of what that output looks like:

import boto3
import sys

SHORT_CODE = "12345"  # TODO: Replace with your short code (e.g., "67890")
POOL_ID = "pool-1234567890abcdef0"  # TODO: Replace with your pool ID from Step 4
CONFIG_SET_NAME = "prod-otp-shortcode"  # TODO: Replace with your configuration set name from Step 3

client = boto3.client("pinpoint-sms-voice-v2")

# Note: For accounts with many resources, implement NextToken pagination
# on describe_* calls. This script assumes results fit in a single page.


def check_short_code_active():
    """Step 1: Verify short code is Active."""
    response = client.describe_phone_numbers(
        Filters=[
            {"Name": "status", "Values": ["ACTIVE"]},
            {"Name": "number-type", "Values": ["SHORT_CODE"]}
        ]
    )
    numbers = [
        n for n in response["PhoneNumbers"]
        if n["PhoneNumber"] == SHORT_CODE
    ]
    assert len(numbers) > 0, f"Short code {SHORT_CODE} not found or not Active"
    print(f"[PASS] Short code {SHORT_CODE} is Active")


def check_keywords_configured():
    """Step 2: Verify HELP and STOP keywords exist."""
    response = client.describe_keywords(OriginationIdentity=SHORT_CODE)
    keyword_names = [kw["Keyword"].upper() for kw in response["Keywords"]]
    assert "STOP" in keyword_names, "STOP keyword not configured"
    assert "HELP" in keyword_names, "HELP keyword not configured"
    print("[PASS] HELP and STOP keywords configured")


def check_configuration_set():
    """Step 3: Verify configuration set exists."""
    response = client.describe_configuration_sets(
        ConfigurationSetNames=[CONFIG_SET_NAME]
    )
    assert len(response["ConfigurationSets"]) > 0, f"Configuration set {CONFIG_SET_NAME} not found"
    print(f"[PASS] Configuration set '{CONFIG_SET_NAME}' exists")


def check_pool_association():
    """Step 4: Verify pool exists and short code is associated to it."""
    response = client.describe_pools(PoolIds=[POOL_ID])
    assert len(response["Pools"]) > 0, f"Pool {POOL_ID} not found"

    # Verify short code is associated to the pool
    assoc_response = client.list_pool_origination_identities(PoolId=POOL_ID)
    identities = [
        oi["OriginationIdentity"]
        for oi in assoc_response["OriginationIdentities"]
    ]
    assert any(SHORT_CODE in oi for oi in identities), \
        f"Short code {SHORT_CODE} not associated with pool {POOL_ID}"
    print(f"[PASS] Pool '{POOL_ID}' exists and short code is associated")


if __name__ == "__main__":
    checks = [
        check_short_code_active,
        check_keywords_configured,
        check_configuration_set,
        check_pool_association,
    ]
    for check in checks:
        try:
            check()
        except Exception as e:
            print(f"[FAIL] {check.__doc__} - {e}")
            sys.exit(1)
    print("\nAll validation checks passed. Ready for production traffic.")

Cleaning up

If you created test resources while following this walkthrough, you can delete them through the AWS End User Messaging SMS console or with the API to avoid confusion with your production configuration. This includes a test configuration set, test pool, or test event destinations used for validation. Do not delete your production configuration set, pool, or keyword settings.

If you requested a test-level MPS increase or spending limit for validation, update these to your production values through a new support case before going live.

Quick reference checklist

Step Action Key API / Service
1 Verify short code is Active and test delivery SendTextMessage
2 Configure keywords and verify message compliance PutKeyword
3 Create configuration set with event destinations CreateConfigurationSet
4 Create pool and associate short code CreatePool, AssociateOriginationIdentity
5 Request MPS increase for expected throughput AWS Support
6 Request spending limit increase AWS Support
7 Restrict destination countries Console / UpdateAccount
8 Set up CloudWatch alarms and dashboards Amazon CloudWatch
9 Track OTP verification success (if applicable) SMS Feedback events
10 Set up cost visibility AWS Cost Explorer, AWS Budgets
11 Plan phased traffic migration Application-level routing
12 Validate production readiness and send All of the preceding

Conclusion

In this post, we walked through how to configure a newly provisioned SMS short code for production use with AWS End User Messaging SMS. The 12 steps cover keyword verification, message compliance, event monitoring, throughput planning, country restrictions, cost visibility, phased traffic migration, and a final production validation.

You can adapt the sequence to your specific use case and volume profile. For the full registration and application process, see A guide to SMS short codes with AWS End User Messaging. To start configuring, navigate to the AWS End User Messaging SMS console. For the full API reference, see the AWS End User Messaging SMS documentation.


About the author

Run isolated sandboxes with full lifecycle control: AWS Lambda introduces MicroVMs

Post Syndicated from Micah Walter original https://aws.amazon.com/blogs/aws/run-isolated-sandboxes-with-full-lifecycle-control-aws-lambda-introduces-microvms/

Today, we are announcing AWS Lambda MicroVMs, a new serverless compute primitive within AWS Lambda that lets you run code generated by users or AI in isolated, stateful execution environments. You get virtual machine level isolation, near-instant launch and resume, and direct control over environment lifecycle and state, all without managing infrastructure or building expertise in complex virtualization technologies. Lambda MicroVMs are powered by Firecracker, the same lightweight virtualization technology that has powered over 15 trillions of monthly Lambda function invocations.

Why customers need this
Over the past few years a new class of multi-tenant applications has emerged that all share the need to hand each end user their own dedicated execution environment in which to safely run code that the application developer did not write. AI coding assistants, interactive code environments, data analytics platforms, vulnerability scanners, and game servers that run user-supplied scripts all fit this pattern. Building that capability today means making a difficult choice. Virtual machines deliver strong isolation but take minutes to start. Containers launch in seconds, yet their shared-kernel architecture requires significant custom hardening to safely contain untrusted code. Functions as a service are optimized for event-driven, request-response workloads, but are not designed for long-running interactive sessions that need to retain environment state across user interactions. That leaves developers either accepting tradeoffs between performance and isolation, or investing significant engineering resources to build and operate custom virtualization infrastructure to achieve isolated execution while delivering low-latency experiences to end-users. This presents an effort that demands deep expertise and pulls engineering time away from the product they are actually trying to build.

Lambda MicroVMs is purpose-built for exactly this gap. Each MicroVM gives a single end user or session its own isolated environment that launches rapidly, retains memory and disk state for the length of the session, and pauses to a low idle cost when the user steps away. Because the same Firecracker technology already underpins AWS Lambda Functions, you inherit the operational maturity of a service that has been running this stack at scale.

Let’s try it out
To get started, I navigated to the AWS Lambda console, where Lambda MicroVMs now appears in the left-hand navigation menu. I first need to create a MicroVM Image.

I packaged a Flask web app and its Dockerfile into a zip file, uploaded it to an Amazon Simple Storage Service (Amazon S3) bucket.

My Flask API – app.py

import logging

from flask import Flask, jsonify

app = Flask(__name__)
logging.basicConfig(level=logging.INFO)


@app.route("/")
def hello():
    app.logger.info("Received request to hello world endpoint")
    return jsonify(message="Hello, World!")


if __name__ == "__main__":
    app.run(host="0.0.0.0", port=5000)

My Dockerfile


FROM public.ecr.aws/lambda/microvms:al2023-minimal
RUN dnf install -y python3 python3-pip && dnf clean all

WORKDIR /app

COPY requirements.txt .
RUN pip install --no-cache-dir -r requirements.txt

COPY app.py .

EXPOSE 5000

CMD ["gunicorn", "--bind", "0.0.0.0:5000", "app:app"]

I used the following command to create my MicroVM Image.

aws lambda-microvms create-microvm-image \
--code-artifact uri=<path/to/s3/artifact.zip> --name <VM_image_name> \
--base-image-arn arn:aws:lambda:us-east-1:aws:microvm-image:al2023-1 \
--build-role-arn <IAM role ARN>

You can also create the MicroVM Image in the AWS Console as in the image above. Once I ran the command, Lambda retrieved the zip, ran the Dockerfile, initialized the application, and took a Firecracker snapshot of the running disk and memory state. Build logs streamed in real time to Amazon CloudWatch under /aws/lambda/microvms/<image-name>, and when the image was ready it appeared in the console with its Amazon Resource Name (ARN) and version number.

aws lambda-microvms run-microvm \
--image-identifier arn:aws:lambda:<region>:<acct>:microvm-image:my-image \
--execution-role-arn arn:aws:iam::<acct>:role/MicroVMExecutionRole \
--idle-policy '{"maxIdleDurationSeconds":900,"suspendedDurationSeconds":300,"autoResumeEnabled":true}'

Launching can also be done via the AWS Console or the CLI. I passed the image ARN and an idle policy configured to auto-suspend after 15 minutes of inactivity and auto-resume on the next incoming request. No networking setup was required. Lambda assigned the MicroVM a unique ID, returned a dedicated endpoint URL, and started a new MicroVM with my Flask app already running, since it was resumed from a snapshot. My Flask app was already running the moment the launch completed. One API call to get a fully initialized, bootstrapped compute environment.

To send traffic, I generated a short-lived auth token with the CLI and attached it to a plain HTTPS request using the X-aws-proxy-auth header. The request landed on my Flask app immediately. I then let the MicroVM sit idle past the suspend threshold, at which point the MicroVM was suspended, with its memory and disk state snapshotted and stored. I then sent another request, and it resumed with the application state fully intact. From the client side, the pause never happened.

How it works
Under the covers, Lambda MicroVMs delivers three capabilities that, until today, no single AWS compute service offered together. The first is virtual machine level isolation, which comes from Firecracker. Each session runs in its own dedicated MicroVM with no shared kernel and no shared resources between users, so untrusted code supplied by one user is contained to their execution environment, without access to other environments or the underlying system. The second is rapid launch and resume. The model is image-then-launch: you create a MicroVM Image by supplying a Dockerfile and code packaged as a zip artifact in Amazon S3, and Lambda runs your Dockerfile, initializes your application, and takes a Firecracker snapshot of the running environment’s memory and disk state. Every subsequent MicroVM launched from that image resumes from the pre-initialized snapshot rather than booting cold, which means launches and idle resumes both achieve near-instant startup latency. Even a multi-gigabyte interactive session comes back online quickly enough to feel responsive to the end user. The third is stateful execution. A running MicroVM retains memory, disk, and running processes across the user’s session. During idle periods, a MicroVM can be suspended – with memory and disk state intact – and resumed when traffic arrives. Installed packages, loaded models, and working filesets are readily available when the user resumes their session. MicroVMs support up to 8 hours of total runtime and can be suspended automatically after a configurable idle window, which makes it straightforward to build products as varied as software vulnerability scans that complete in minutes, data analytics applications that run for hours, and interactive coding sessions with extended idle periods. As Lambda MicroVMs are started from pre-initialized snapshots, applications generating unique content, establishing network connections, or loading ephemeral data during initialization may need to integrate with service-provided hooks for compatibility.

Lambda MicroVMs is a new resource within AWS Lambda, with a distinct API surface. Lambda Functions remain the right choice for event-driven, request-response workloads, and Lambda MicroVMs is purpose-built for multi-tenant applications that need to hand each end user or session their own isolated environment to execute user- or AI-generated code. The two complement each other. An application using Lambda Functions for its event-driven backbone can call into Lambda MicroVMs for the steps that need to run untrusted code in isolation. You bring the application, and the service delivers the execution environment.

Now available
AWS Lambda MicroVMs is available today in the US East (N. Virginia, Ohio), US West (Oregon), Europe (Ireland) and Asia Pacific (Tokyo) Regions, on the ARM64 architecture, with up to 16 vCPUs, 32 GB of memory, and 32 GB of disk per MicroVM. Idle MicroVMs can be suspended explicitly through an API call or automatically through a lifecycle policy, which reduces the running cost while preserving full state for fast resume. Pricing details can be found on the AWS Lambda pricing page.

To get started, visit the AWS Lambda console, or learn more on the Lambda MicroVMs product page. For documentation, see the Lambda MicroVMs Developer Guide.

Modernizing financial analytics with Amazon SageMaker Unified Studio

Post Syndicated from Umang Aggarwal original https://aws.amazon.com/blogs/architecture/modernizing-financial-analytics-with-amazon-sagemaker-unified-studio/

Avanse Financial Services is one of India’s leading education loan providers. Their Data Engineering Team had built a data lake on AWS using Amazon Simple Storage Service (Amazon S3), Amazon Athena, and AWS Glue for data ingestion and processing. However, their analytics and reporting layer ran on an external analytics application that wasn’t integrated with AWS. Data had to be copied from Amazon S3 into this external application before analysts could run any report, its license consumed a significant portion of their budget despite low utilization, and every integration with AWS services required custom-built pipelines.

After evaluating their options, Avanse migrated to a cloud-native lakehouse architecture using Amazon SageMaker Unified Studio, which unified their data engineering, analytics, and artificial intelligence (AI) workflows in a single governed environment on AWS. In this post, we walk through their migration journey so you can adapt their approach to your own environment.

Why Avanse chose to modernize

The separation between their AWS data lake and their external analytics application created five problems:

  1. Daily data synchronization bottleneck. Every report required a 4-hour batch copy from Amazon S3 into the external analytics application before analysts could query it. Business decisions were based on data that was at least a day old.
  2. Fixed licensing costs disconnected from usage. The external analytics application charged an annual fee regardless of how many queries analysts ran. Avanse needed usage-based pricing that matched what they actually consumed, not a fixed fee for capacity they weren’t using.
  3. Limited auditability. The external analytics application ran on a shared server where different business units (risk, collections, portfolio management) shared the same resources. It lacked granular audit trails, making it difficult to trace who accessed what data and when, or to allocate costs per team.
  4. No centralized data discovery. Although AWS Glue Data Catalog managed schema metadata for the data lake, the external analytics application couldn’t access it. Analysts working in that application relied on folder structures and manual documentation to find the right datasets, slowing onboarding and increasing the risk of using outdated data.
  5. Disconnected from AWS services. The external analytics application couldn’t query data in Amazon S3 or use AWS Glue catalogs natively. Every data flow required connectors and custom-built pipelines, adding maintenance overhead.

Additionally, some datasets were stored on Network File System (NFS) storage outside of Amazon S3, creating another data silo that needed to be consolidated.

Avanse chose Amazon SageMaker Unified Studio because it addressed all five challenges: direct querying of data in Amazon S3 avoiding synchronization, usage-based compute through Amazon Athena and Amazon EMR Serverless, project-based isolation with per-project billing, lineage tracking with AWS IAM Identity Center, and native integration with their existing AWS services.

Solution overview

The core architectural change was moving from a two-application model to a single integrated stack:

Previous architecture
Avanse’s data ingestion and processing ran on AWS (Amazon S3, AWS Glue, Athena), but analytics and reporting ran on an external analytics application. Data had to be batch-copied from Amazon S3 into this external application daily before analysts could query it. Each system had its own access controls, and there was no shared catalog or lineage tracking between them.
New architecture
Analytics now run directly against data in Amazon S3 through Amazon SageMaker Unified Studio. There’s no data copy step. Analysts query the same data that the ingestion pipelines produce, using Athena for SQL and EMR Serverless for large-scale processing. Governance, access control, and lineage are centralized through IAM Identity Center and SageMaker Catalog.

The following diagram illustrates the target architecture. It follows a lakehouse pattern, storing data in open formats on Amazon S3 while maintaining ACID transaction support for the consistency financial regulators expect.

Three-layer lakehouse architecture for Avanse on AWS, showing the data layer with Amazon S3 and AWS Glue Data Catalog, the compute layer with Amazon SageMaker Unified Studio, AWS Glue ETL, AWS Lambda, Amazon EMR Serverless, Amazon SageMaker AI, and Amazon Bedrock, and the governance layer with AWS IAM Identity Center, SageMaker Catalog, and Amazon DataZone

The architecture has three layers:

  1. Data layer – Amazon S3 stores data in open formats (Parquet, Delta Lake) with S3 Intelligent-Tiering for automatic cost optimization. AWS Glue Data Catalog maintains schema metadata, making data discoverable across tools.
  2. Compute layer – Amazon SageMaker Unified Studio provides project-based workspaces organized by business function. Collections uses the built-in SQL Query Editor powered by Athena, Risk Reporting uses JupyterLab for interactive analysis, and MIS runs large-scale Spark jobs through Amazon EMR Serverless. AWS Glue ETL handles data transformations and AWS Lambda provides event-driven triggers for report generation. For machine learning (ML) workloads, Amazon SageMaker AI supports model training and deployment, with Amazon Bedrock available for generative AI capabilities such as enhancing risk narratives.
  3. Governance layer – IAM Identity Center provides SSO and audit logging across workspaces. SageMaker Catalog serves as the business glossary with data lineage tracking and access controls. Amazon DataZone connects components through a common metadata layer.

Migration journey

Avanse followed a five-phase approach. The timelines can be adapted to your environment, but the systematic progression from validation through production deployment is key.

Phase 1: Technical validation (72-hour workshop)

Avanse started with a focused 72-hour workshop using isolated SageMaker environments where developers could experiment without impacting production. Their team tested SQL analytics against existing Athena tables and validated that Python and PySpark could replicate their existing analytics workflows.

The team confirmed that querying data directly in Amazon S3 addressed their synchronization bottleneck entirely. The 4-hour daily data copy was no longer necessary, which validated the migration approach.

Phase 2: Data migration and storage optimization

Avanse migrated datasets from NFS storage and legacy analytics formats into Amazon S3, consolidating the data into a single location. They implemented S3 Intelligent-Tiering, which automatically moves data between access tiers based on usage patterns, optimizing costs without impacting retrieval performance.

They replaced legacy analytics connectors with native Athena workgroups within SageMaker Unified Studio, avoiding data synchronization entirely. Source data remained in Amazon S3, queryable by both Athena SQL and SageMaker notebooks, establishing a single source of truth.

Phase 3: Compute modernization

Avanse moved from a shared analytics server to project-based isolation in SageMaker Unified Studio. Each business function (Risk Reporting, Collections, MIS) received its own project with dedicated compute spaces running JupyterLab. Project-specific IAM execution roles provided access controls and cost allocation per business unit.

A single browser-based URL with multi-factor authentication (MFA) now provides access to SQL analytics using the built-in query editor, ML development in JupyterLab notebooks, and big data processing through Amazon EMR Serverless. This replaced the need for local analytics client installations.

Phase 4: Governance implementation

Avanse deployed SageMaker Catalog as their central business data catalog. Analysts now discover approved datasets through semantic search rather than navigating folder structures or relying on manual documentation. They mapped technical Athena table names to business terms. For example, analysts search for “collection efficiency” and find the relevant tables with descriptions, schemas, and lineage.

Lineage capture traces each metric in risk reports back to source tables, transformations, and intermediate datasets. Every action (notebook execution, SQL query, data access) is tied to IAM Identity Center users, creating the comprehensive audit trail their compliance team needed.

Phase 5: Use case migration

Rather than attempting a big-bang migration, Avanse moved critical workflows one at a time:

Portfolio MIS (Monthly/Fortnightly)
Previously required the daily 4-hour data copy from Amazon S3 into the external analytics application before report generation could begin. Avanse avoided the data synchronization step entirely and now generates MIS reports by querying existing Athena tables directly in Amazon S3. Because the source data was already on AWS, there was no need to involve the external application for this activity. Report generation dropped from hours to under 30 minutes.
Collection Efficiency and Bounce Calculation
Ported complex legacy analytics procedures for calculating metrics like collection efficiency and bounce rates to event-driven processing using AWS Glue ETL, AWS Lambda, and PySpark jobs for high-volume data aggregation. The serverless execution model charges only for compute time consumed.
EDW Risk Reporting
Large-scale regulatory joins of Enterprise Data Warehouse assets previously ran as legacy scheduled procedures. These now run as SQL queries in the SageMaker Unified Studio query editor, where analysts execute them on-demand or schedule them through Athena workgroups. The distributed query engine handles complex multi-table joins spanning millions of rows.
Scorecard Generation
Model building shifted from the external analytics application to SageMaker AI workflows. Data scientists use JupyterLab with Python libraries and deploy models directly to SageMaker endpoints, avoiding data movement between separate environments.

Overcoming technical challenges

One technical challenge was code migration. Avanse’s analytics code base contained years of accumulated proprietary scripts and procedures. Direct line-by-line translation was not practical. Instead, they took a pragmatic approach: basic data transformations moved to SQL in Athena, complex business logic was rewritten in PySpark for scalability, and statistical procedures were replaced with Python libraries like pandas and scikit-learn. The approach was to focus on what the code accomplishes, then implement it using cloud-native patterns.

The other technical challenge was performance validation. The team needed to confirm that querying data in Amazon S3 would deliver acceptable performance compared to the external analytics application’s in-memory processing. Queries against Parquet-formatted data in Amazon S3 using Athena delivered comparable performance for standard reporting workloads, while avoiding the 4-hour daily data synchronization step entirely. For large-scale regulatory joins spanning millions of rows, Amazon EMR Serverless provided distributed Spark processing that completed in minutes rather than the hours required in the external application.

Key outcomes

Area Result
Licensing costs Avoided external analytics application fees entirely
Storage costs Reduced through S3 Intelligent-Tiering, which automatically moves data between access tiers based on usage patterns
Report generation From over 4 hours (including data synchronization from Amazon S3 to the external analytics application) to under 30 minutes with direct Amazon S3 querying
Compliance audits From weeks of manual investigation to days with automated lineage reports
Compute costs Usage-based serverless model replaced always-on external analytics infrastructure
Collaboration Unified browser-based environment for data scientists, analysts, and engineers

“By adopting SageMaker Unified Studio, we as the Data Team eliminated legacy licensing costs, reduced storage and compute expenses with a serverless, usage-based model, and accelerated our periodic report generation. At the same time, we transformed compliance and collaboration by cutting audit timelines while unifying our teams in a single, efficient data environment.” – Komal Thakkar, AVP – Lead, Data Engineering, Avanse Financial Services

Best practices

Based on their experience, Avanse recommends:

  • Start with a workshop. Validate your specific use cases in a 72-hour technical validation before committing to full migration.
  • Migrate use cases, not code. Focus on what your analytics accomplish, then implement using cloud-native patterns rather than translating legacy scripts line by line.
  • Invest in governance early. Implement the data catalog and lineage tracking from day one.
  • Embrace project-based isolation. Organize around business functions for clear cost allocation and security boundaries.
  • Document business logic. Use migration as an opportunity to capture undocumented knowledge in the business glossary and dataset descriptions.

Conclusion

Avanse’s migration from an external analytics application to Amazon SageMaker Unified Studio consolidated their analytics stack into a single integrated environment on AWS. By querying data directly in Amazon S3 instead of copying it into the external application, they alleviated their biggest operational bottleneck. Project-based isolation replaced a shared server model, giving each business unit independent compute and clear cost visibility. And centralized governance through SageMaker Catalog and IAM Identity Center gave their compliance team the audit trails they had been missing.

The serverless, usage-based model means Avanse no longer pays for idle capacity. The lakehouse architecture supports new analytics patterns as they emerge, and native integration with AWS services, including generative AI through Amazon Bedrock, positions them to adopt new capabilities as their needs evolve.

Next steps

Start your analytics modernization journey by scheduling a 72-hour technical validation workshop. Contact your AWS account team to discuss your migration approach.

For more information, see:

Upgrading Lambda function runtimes at scale with AWS Transform custom

Post Syndicated from Brian Krygsman original https://aws.amazon.com/blogs/compute/upgrading-lambda-function-runtimes-at-scale-with-aws-transform-custom/

When you create an AWS Lambda function, you choose the runtime that Lambda will use to run your code. This includes the base language version and supporting libraries. Lambda runtimes follow a published deprecation schedule. This means that you must periodically upgrade your function’s runtime.

Running on a deprecated runtime means potential security exposure, loss of AWS Support, and compliance challenges. For teams managing dozens of functions, this is a manageable maintenance task. For teams managing hundreds or thousands, it becomes a significant engineering effort that competes with feature work.

You can modernize your code and configurations with AWS Transform custom, an Agentic AI service purpose-built for code modernization. It fits into each stage of a runtime upgrade: surfacing risk, confirming test coverage, code transformation, and validation. The same workflow scales from a single function to an entire organization. You can use AWS-provided transformations or create your own, for compliance or compatibility. You can give it feedback to enforce your standards. You’re charged only for active agent work during server-side operations, not for user idle time or client-side processing.

This post addresses two audiences. If you work in an application team, you will learn how to use AWS Transform custom to upgrade your functions with confidence. If you’re part of a centralized platform team, you will see how to orchestrate Lambda upgrade campaigns at enterprise scale.

The upgrade challenge

Python and Node.js are two of the most widely used Lambda runtimes, and both have important recent or upcoming deprecation timelines.

Runtime Deprecation date
Node.js 20 April 30, 2026
Node.js 22 April 30, 2027
Python 3.9 December 15, 2025
Python 3.10 October 31, 2026

Sometimes a runtime upgrade requires changing your functions’ configuration in your infrastructure-as-code template or in the Lambda console. Other times, you also need to upgrade dependencies or even make code changes.

For example, in Node.js 24 AWS removed support for callback-based function handlers, in favor of the more modern async/await pattern which Lambda has supported since Node.js 8. Functions using the old pattern must be refactored. This is a behavioral change which affects every callback-based handler in the code base.

Before:

exports.handler = function(event, context, callback) {
    const result = processEvent(event);
    callback(null, result);
};

After:

exports.handler = async function(event) {
    const result = await processEvent(event);
    return result;
};

Applying this type of transformation across multiple Lambda functions used to require manual code changes. With AWS Transform custom, you can automate the upgrade to free your team’s capacity and focus for differentiated work.

AWS Transform custom for application teams

We assume you have AWS Transform custom already set up. For guidance, see the AWS Transform custom documentation. You can also use AWS Transform custom through the Kiro Power.

Prerequisites

Make sure you have the following configured locally:

Run a documentation transform

For your first transform, you can run the AWS-provided “AWS/comprehensive-codebase-analysis” transformation on a representative function or code base. This produces a prioritized view of the upgrade effort before a single line of code is changed, helping you plan your upgrade. Better-documented functions are easier to assess, maintain, and hand off. Running a documentation transform is a low-risk first step: it doesn’t change function behavior and lets you build familiarity with the AWS Transform custom workflow.

When you run the code analysis transformation, add additionalPlanContext to inform AWS Transform custom that you plan to upgrade your Lambda function runtimes. It can flag functions most likely to require code changes. For example, functions with callback-based handlers, complex async/callback code, or low test coverage.

atx custom def exec \
    --code-repository-path . \
    --transformation-name AWS/comprehensive-codebase-analysis \
    --configuration additionalPlanContext="Include analysis of Lambda function runtime upgrade to Node.js 24"

The following figure is a screenshot from running the preceding command on a sample code base.

Example AWS Transform output from documentation transform

Validation planning

Before an upgrade, you must verify correctness. This provides the confidence that you haven’t introduced new issues by upgrading. Test coverage from unit and integration tests helps with verification. A passing test suite can enforce the behavioral contract for the transformed code and help prevent problems.

Observability tools like metrics and alarms can help you validate your changes after they’ve been deployed. They can help you detect when breaks happen and are critical for finding the underlying cause.

If you’re not comfortable with your test or monitoring coverage, you can use AI agents to help. You can create a custom transformation definition in Transform custom to add or improve your tests or add alarms to your infrastructure as code (IaC) template. You can also use Kiro or other agents to generate tests from function specs, covering expected inputs, outputs, and error paths.

Transform

Now that you’ve used the documentation transformation to familiarize yourself with the tool and confirmed you have a way to validate your upgrade, you can use AWS Transform custom to upgrade your functions to a new runtime.

To apply the transform, use the AWS Transform custom CLI or Kiro Power. The example command below runs the “AWS/lambda-nodejs-runtime-upgrade” transformation against the code in the current directory. You can use additional switches to automatically trust all tools and run non-interactively.

atx custom def exec \
    --code-repository-path . \
    --transformation-name AWS/lambda-nodejs-runtime-upgrade \
    --configuration additionalPlanContext="Target Node.js 24"

Transform custom follows the instructions in the transform definition and additional plan context you specify. You can tell it to focus on a specific Lambda function in your code repository or upgrade all the functions it finds. Transform custom identifies callback-based handlers and refactors them to async/await. It handles edge cases including callbackWaitsForEmptyEventLoop and mixed async/callback patterns.

Dependency analysis flags packages with known incompatibilities with Node.js 24 and replaces them. Configuration updates change the Lambda runtime from nodejs22.x to nodejs24.x. AWS Transform custom self-debugs on build or test errors and commits changes to git incrementally on a separate transformation branch. You can also share feedback along the way, which is captured as Knowledge Items that can be applied to future transformations.

The following figures are screenshots from running the preceding command on a sample code base.

Screenshot of AWS Transform custom CLI output. It shows a sequence of tasks relating to Node.js upgrade. AWS Transform explains each task in natural language and states which tools are being used.

Screenshot of AWS Transform custom CLI output. It shows a transformation summary report at the end of the documentation transformation run. The report describes the status of each stage in the process (all ‘Yes’) and the summary summarizes the files to be upgraded.

Validate

AWS Transform custom validates defined exit criteria before marking the transformation complete.

Exit criteria can include:

  • All handlers run without errors on Node.js 24.
  • All tests pass, including generated callback behavior tests.
  • All dependencies confirmed compatible with Node.js 24.
  • Runtime configuration updated to nodejs24.x.
  • Additional requirements added with additionalPlanContext.

The newly transformed code remains in the transformation branch until you’re ready to merge and deploy. You can review logs of the transformation process captured by Transform. You can also run additional validation on the new code, including security scans or more complex test suites like performance or penetration tests. Because the changes are on a separate git branch, you can follow your standard code review, testing, and deployment processes. For extra safety, you can deploy using Lambda traffic shifting with Versions and Aliases, which you can use to roll back.

AWS Transform custom for platform teams

The preceding workflow works well for application teams managing tens or hundreds of functions across a few repositories. But what if you’re a platform team coordinating upgrades across thousands of functions in multiple AWS accounts?

In that case, you must orchestrate upgrades across teams and repositories. In some cases, you might apply the upgrades yourself. In other organizations, you focus on coordination and keep ownership of the upgrades distributed. In both approaches you need visibility to the breadth of the challenge, and tools to monitor progress. Transform custom campaigns can help.

Initiating and tracking an upgrade campaign

Platform teams create campaigns through the AWS Transform custom web application. Log in to the web application, create a workspace, and describe your goal. For example, “I want to upgrade all Lambda functions from Node.js 22 to Node.js 24.” AWS Transform custom displays matching transformation definitions and generates a campaign with a unique campaign ID and CLI command. Note: the command includes --trust-all-tools and --non-interactive switches, meaning it will run without tool prompts or user assistance.

atx custom def exec \
    --code-repository-path <path-to-repo> \
    --non-interactive \
    --trust-all-tools \
    --campaign <campaign-id> \
    --repo-name <repo-name> \
    --add-repo

You can identify candidate functions in your organization with AWS Trusted Advisor, the AWS CLI, Amazon CloudWatch, or AWS Config. To distribute upgrade responsibility, map the functions to owners using Tags or deployment metadata in AWS CloudTrail or your continuous integration and delivery (CI/CD) pipeline. Then share the campaign command with them.

Run the command against each target repository. When the command runs, it automatically registers the repository with the campaign. It then begins the upgrade based on the configuration the platform team chose when creating the campaign.

The AWS Transform web application dashboard tracks campaign progress at a glance. It shows total repositories registered in the campaign and how many are completed, in progress, or not started. It also reports success and failure rates along with transformation results and validation summaries.

The following figures show examples of dashboard visualizations.

AWS Transform console screenshot showing progress of a transformation campaign. The pie chart shows 10 of 10 repositories upgraded. The data shows 73 files and 407 lines of code modified, and the validation rate is 100%.

AWS Transform console screenshot showing a breakdown of files changed and lines of code modified for each of 10 repositories in the upgrade campaign.

AWS Transform report showing estimated saved time of 326 hours.

Scaling with cloud infrastructure

AWS also provides Open Source infrastructure that can automate parallel transform execution using AWS Batch and AWS Fargate. This solution moves processing to the cloud from individual developer machines to help you move more quickly, and includes:

  • REST API: submit single transformations or batches of thousands.
  • Serverless compute: AWS Batch with Fargate runs transformation jobs in parallel.
  • Automatic credential management: AWS Identity and Access Management (IAM) credentials auto-refresh, avoiding long-lived access keys.
  • Multi-language container: pre-built container supporting Java, Python, and Node.js with build tools included.

The default configuration supports up to 128 concurrent transformation jobs, with automatic queuing and resource management. For detailed implementation guidance, cost information, and code, see Building a scalable code modernization solution with AWS Transform custom.

Note: AWS Batch and Fargate incur additional charges beyond AWS Transform custom. See README for cost details.

Clean up

AWS Transform custom charges for active agent work during server-side operations. To avoid ongoing charges, stop any running transformations. See the AWS Transform pricing page for details.

If you deployed the scaling infrastructure, follow the cleanup instructions.

Conclusion

You can streamline Lambda runtime upgrades with AWS Transform custom, an Agentic AI service purpose-built for code modernization.

Customers with a backlog of existing functions to upgrade can use Transform custom to coordinate and streamline bulk upgrades across their organization. Transform custom also helps you move from the tail of the release cycle to the leading edge. By making runtime upgrades faster and more straightforward, you can stay ahead of the challenges of deprecation and take advantage of better performance and new features from newer runtimes.

AWS Transform custom fits into each stage of the software development lifecycle: surface risk early, confirm validation coverage, transform, validate, deploy. It can work with your existing code management, build, test, and deployment, giving you control over changes using your existing processes and tools.

Start with the documentation transform on a function today to get hands-on with AWS Transform custom. Review the currently-deprecated runtimes and make a plan to upgrade.

For more information, see AWS Transform custom documentation and Getting Started topic in the AWS Transform User Guide.

For more serverless learning resources, visit Serverless Land.


About the authors

Brian Krygsman

Brian Krygsman

Brian is a Senior Solutions Architect at Amazon Web Services. He has an application development background and technical depth in event-driven architectures and serverless development. He works with enterprise customers to effectively leverage cloud when building scalable, fault-tolerant, high-performant, cost-effective solutions.

Jonathan Tuliani

Jonathan Tuliani

Jonathan is a Principal Product Manager with AWS Lambda. Based in Dublin, Ireland, Jonathan is responsible for Lambda’s programming language runtimes. He bridges between customers and engineering teams to define strategy, prioritize investments, and design features that solve real-world customer problems.

Reducing SMS OTP fraud with Vonage network-powered solutions and Amazon Cognito

Post Syndicated from Tito Milla original https://aws.amazon.com/blogs/architecture/reducing-sms-otp-fraud-with-vonage-network-powered-solutions-and-amazon-cognito/

User authentication remains one of the most targeted touchpoints in application security. With the industrialization of fraud threats by generative AI, cybercrime costs are expected to reach $23 trillion in 2027, an increase of 175 percent from 2022. 20 percent of fraud is attributed to synthetic identity and authentication exploits, with account takeover (ATO) surging 141 percent since 2021.

But the damage goes beyond security. SMS One-time passcodes (OTPs) achieve only approximately 80 percent conversion on authentication flows, meaning 1 in 5 legitimate users is lost at the point of verification. Enterprises absorb hundreds of thousands of password recovery helpdesk tickets annually, representing significant support costs tied to OTP-based verification. Every abandoned authentication attempt today represents an opportunity to maximize your conversion rates across checkout, account recovery, and onboarding flows. The industry has long assumed that stronger security requires more user friction. That isn’t a law of physics. It’s a limitation of the tools available. Mobile operator network data removes that constraint and provides stronger identity assurance and a smoother experience, not one at the expense of the other.

In this post, we show how Vonage network-powered solutions work with Amazon Cognito to enhance many mobile-first use cases with network-level identity verification. Vonage network-powered solutions are a composable stack of real-time mobile operator intelligence, silent authentication, and integrated fraud protection, which uses the CUSTOM_AUTH flow to complete identity verification in under 5 seconds, with zero user interaction.

About Vonage

Vonage, part of Ericsson, is an AWS Partner with multiple AWS Marketplace listings. The company provides enterprise and CIAM deployments with cloud-based access to mobile operator network APIs, including real-time mobile identity and authentication across key regions. These complement Vonage’s global communications, voice, and video APIs backed by Ericsson’s global telecommunications infrastructure.

What network-powered means and why it matters

Before diving into architecture, it’s worth being precise about what separates Vonage’s network-powered solutions from the identity and fraud tools enterprises already have in their stack.

Most identity verification signals today are derived from aggregated, cached, or behavioral data. Traditional phone number lookup services query static databases that may be days or weeks out of date. Device fingerprinting analyzes browser characteristics that might be spoofed. Behavioral biometrics builds models from historical sessions. This is useful, but a lagging indicator by definition.

Enterprise customers who implement Vonage’s network-powered solutions operate from a fundamentally different layer: real-time data sourced directly from mobile network operators (MNOs). When you query whether a SIM was recently swapped, you’re querying the network that performed the swap. When Silent Authentication verifies a user, the proof of possession is the cellular data session itself. This session can’t be phished, intercepted, or socially engineered.

In fraud scenarios where SIM swaps are weaponized for account takeover (ATO), “recently” means minutes or hours, not days. Static databases refreshed weekly are not detecting these events. They’re logging them after the fact. Real-time operator queries close that window entirely.

The three pillars: Identity Insights, Verify, and Fraud Defender

Vonage network-powered solutions combine three API service components into a composable security stack that integrates with Amazon Cognito through the CUSTOM_AUTH flow:

1. Identity Insights: Pre-verification intelligence

Identity Insights runs before verification channels are initiated, surfacing real-time operator signals that are directly actionable in authentication policy decisions. The following list shows a representative set of JSON elements that might be returned by a request. Customers have the option to select which data is most valuable given a specific authentication use case and industry combination.

  • format and network_type: Filters invalid numbers, VoIP, landline, and premium-rate numbers used in synthetic account creation and bot-driven fraud.
  • sim_swap: Detects SIM swaps within a configurable look-back window, a leading indicator of ATO events in progress.
  • subscriber_match: Compares subscriber identity (name, address) against operator Know Your Customer (KYC) records.
  • device_swap: A recent change in the mobile device associated with a phone number signals that a bad actor might have taken control of the SIM card. (coming soon)
  • recycled_number: Numbers previously deactivated and reassigned to a new subscriber can trigger false identity matches in onboarding flows, creating risk in account creation. (coming soon)

These pre-checks trigger your defined risk policy: step-up challenge, hard block, or silent logging. Critically, fraudulent attempts are identified and blocked before a single OTP is sent, before verification costs are incurred, and before fraud processing overhead is generated.

2. Verify with Silent Authentication: Alleviating the friction tax

Every additional step a user must finish during authentication carries a measurable cost: abandoned sign-ups, failed conversions, and support tickets from users who don’t receive or mistyped a code. We call this cumulative loss the friction tax. For SMS OTP flows with approximately 80 percent completion rates, the friction tax means roughly 20 percent of legitimate users drop off before they ever reach your application.

After a number passes the risk pre-checks, the Verify API delivers the authentication challenge. The primary authentication method is Silent Authentication.

When a user initiates sign-in from a mobile device, Vonage routes an HTTP request through the user’s cellular data connection. The mobile operator confirms that the SIM registered to the phone number matches the session making the request. The exchange happens in the background, in seconds. The user doesn’t see, type, copy, or enter any code.

If Silent Authentication can’t finish or is unavailable, Verify automatically falls back to traditional SMS, RCS, Voice, WhatsApp, or email, remaining transparent to the user.

Key benefit: Silent Authentication alleviates the three primary exploit vectors against SMS OTP: SIM swap (bad actor receives the code), SS7 interception (message diverted in transit), and social engineering (user tricked into sharing the code). All without additional input from the end user.

3. Fraud Defender: Protecting the verification channel

Fraud Defender addresses a threat familiar to enterprise finance teams: artificially inflated traffic (AIT) and SMS pumping. Automated systems trigger high volumes of OTPs sent to premium-rate numbers that bad actors control. At enterprise verification volumes, these events can run undetected for extended periods.

Fraud Defender provides real-time traffic monitoring and intelligent blocking at the point of outbound delivery, intercepting these malicious events before costs accumulate. The financial impact is immediate and measurable. Fraud Defender typically absorbs its own cost in toll fraud prevention within the first billing cycle. For most enterprises, it quickly becomes a net revenue-positive investment. Vonage customers have collectively saved over $3M in SMS-related fraud costs since deployment. The savings continue to compound as the blocking algorithm evolves to counter new exploit patterns. For Verify customers, the value is even more compelling: Fraud Defender activates automatically with the Vonage Verify API at no additional cost. This makes it one of the highest-ROI fraud protections available.

Prerequisites

To implement this solution, you need:

  • An AWS account with permissions to create and manage Amazon Cognito, AWS Lambda, AWS Secrets Manager, Amazon CloudWatch, and AWS WAF resources.
  • An Amazon Cognito user pool (existing or new).
  • A Vonage API account with access to Identity Insights and Verify APIs.
  • AWS Command Line Interface (AWS CLI) or AWS Serverless Application Model (AWS SAM) CLI installed and configured.
  • For client integration: the Vonage Silent Authentication SDK for your mobile platform (iOS/Android).

Solution architecture with Amazon Cognito

Enterprise customers that integrate the Vonage solution use the Amazon Cognito CUSTOM_AUTH flow, which uses three AWS Lambda functions that orchestrate the solution stack without changing your existing user pool configuration or downstream service integrations.

Architecture diagram showing the Risk-Adaptive Customer Sign-In flow with layers including user devices, edge protection with Amazon CloudFront and AWS WAF, Amazon API Gateway, identity layer with Amazon Cognito, verification layer with Vonage Identity Insights, Verify API, and Fraud Defender, and the carrier network with Mobile Network Operators.

Architecture components

The solution connects five layers, each handling a distinct step in the authentication flow:

  • Client app (mobile/web) – Initiates the CUSTOM_AUTH flow with the Vonage Silent Authentication SDK, follows check_url redirects over the cellular network, and submits the verification code back to Amazon Cognito.
  • Amazon Cognito user pool – Orchestrates the CUSTOM_AUTH challenge flow and issues JWT tokens upon successful verification.
  • AWS Lambda triggers – Define Auth Challenge (orchestrator), Create Auth Challenge (calls Vonage APIs), and Verify Auth Challenge (validates response).
  • Vonage Network APIs – Identity Insights pre-check, Verify with Silent Auth and OTP (built-in failover), and Fraud Defender (automatic).
  • Mobile network operators – SIM-level identity verification through CAMARA/Open Gateway APIs.

Authentication flow

The following steps represent an authentication workflow sequence between Amazon Cognito and Vonage network-powered solutions:

  1. The client calls InitiateAuth with CUSTOM_AUTH, passing the user’s phone number.
  2. The Define Auth Challenge Lambda function instructs Amazon Cognito to issue a CUSTOM_CHALLENGE.
  3. The Create Auth Challenge Lambda function calls Identity Insights for pre-verification risk assessment. If the number passes pre-checks, Lambda calls Vonage Verify to initiate Silent Authentication and returns the check_url to the client.
  4. Upon receiving the check_url, the client opens an HTTPS connection to it, triggering HTTP redirects to the mobile carrier’s network for direct mobile-device-to-mobile-network-operator verification. Upon completion, the client receives a verification code from the operator.
  5. The client calls RespondToAuthChallenge with the code.
  6. The Verify Auth Challenge Lambda function submits the code to Vonage’s check endpoint. On success, it returns answerCorrect = true and Amazon Cognito issues the appropriate session token.

Sequence diagram showing the User Login flow with SIM-swap pre-check using Vonage Identity Insights and Silent Authentication via Vonage Verify, orchestrated through the Amazon Cognito CUSTOM_AUTH flow with Lambda triggers.

Coexistence and phased rollout

A critical design principle: zero disruption to existing infrastructure. The Vonage Network API plugs into the Amazon Cognito CUSTOM_AUTH flow without changes to your existing user pool, app client configurations, or downstream service integrations. Deployment requires a single sam deploy command.

This design approach allows for a phased rollout. Start with the highest-risk journeys (password recovery, high-value transactions) where security ROI is clearest, then expand to daily login and onboarding as you measure impact. Traditional SMS, RCS, and Voice OTP remain options for lower-risk flows during the transition.

Risk-aware workflows by journey type

The strategic value of combining Vonage’s network-powered solutions with the Amazon Cognito policy-driven CUSTOM_AUTH flow is context-aware authentication calibrated to actual risk. CRITICAL journeys are recommended for the first phase of implementation as they aim to meaningfully mitigate synthetic identity and account takeover. The following table describes risk-aware workflows by journey type.

Journey Risk Vonage Workflow
New account signup CRITICAL Identity Insights filters invalid/non-mobile numbers + Subscriber Match validates KYC → Silent Auth for zero-tap onboarding
Daily login MEDIUM SIM swap recency + device consistency check → Silent Auth passively, step-up only on elevated signals
Password recovery, profile change (contacts), 2FA settings change HIGH Mandatory SIM swap hard-check (tight lookback window) + Subscriber Match → Silent Auth required, no passive bypass
High-value transaction CRITICAL Full signal stack (line type, SIM swap, subscriber match) → Silent Auth + secondary challenge if risk elevated

Low-risk actions (for example, viewing account details, browsing content, or checking order history) generate no friction and no unnecessary verification cost. High-risk actions trigger the full assurance stack. The calibration is policy-driven and configurable per journey.

Implementation considerations

Configuring Amazon Cognito starts with setting up the user pool to allow the CUSTOM_AUTH authentication flow and accept phone numbers as the primary sign-in attribute. After the user pool is in place, associate the three required Lambda functions with their corresponding Amazon Cognito trigger hooks and store your Vonage API credentials in AWS Secrets Manager.

Layer in security from the start, following the AWS Well-Architected Security Pillar. Scope each Lambda function’s AWS Identity and Access Management (IAM) role to only what it needs: Amazon Cognito trigger invocations and AWS Secrets Manager access. Enforce TLS 1.2+ on all communication for encryption in transit. For observability, turn on Amazon CloudWatch logging on each Lambda function and turn on AWS CloudTrail to capture Amazon Cognito API audit trails. Finally, deploy AWS WAF with rate-limiting rules in front of the authentication endpoint to protect against brute-force attempts.

To configure the solution, follow these steps:

  1. Set up the Amazon Cognito user pool to allow the CUSTOM_AUTH authentication flow.
  2. Configure the user pool to accept phone numbers as the primary sign-in attribute.
  3. Associate the three required Lambda functions with their corresponding Amazon Cognito trigger hooks.
  4. Store your Vonage API credentials in AWS Secrets Manager.

Important: This solution creates AWS resources that incur charges. These include Amazon Cognito (per monthly active user), AWS Lambda (per invocation), AWS Secrets Manager (per secret per month), Amazon CloudWatch Logs, AWS CloudTrail, and AWS WAF (per rule and request). See the pricing page for each service and delete resources when no longer needed.

Privacy and compliance

The architecture is designed so that PII doesn’t leave the mobile operator. Subscriber Match performs a comparison within the operator’s environment and returns only a match score. The underlying subscriber data isn’t transmitted. Silent Authentication operates without PII exchange. The cellular session is the credential.

  • GDPR: Only match scores are returned. No subscriber PII is stored or transmitted, supporting GDPR data minimization.
  • PSD2 / Open Banking: Silent Authentication qualifies as a possession-factor for Strong Customer Authentication (SCA).
  • HIPAA: Subscriber Match supports identity assurance for healthcare applications.
  • DORA: Multi-channel fallback achieves > 99.9 percent verification availability.
  • CCPA: Same data-minimization architecture as GDPR.

Production results: Lydia Solutions

Lydia Solutions, one of Europe’s fastest-growing mobile financial services applications, deployed Vonage Verify with Silent Authentication in October 2024. The results demonstrate the real-world impact at scale, including up to 50 percent reduction in latency when compared to Lydia Solutions’s previous authentication services.

“Vonage Verify with Silent Authentication has been a real innovation for us. The solution has elevated our ability to deliver a simpler, seamless and more secure user experience while protecting against increasingly sophisticated threats and fraud patterns.”

— William Brulin, Senior VP, Lydia Solutions

Lydia’s results sit at the high end of outcomes observed. Across deployments in ecommerce, digital banking, and consumer services, conversion improvements of 2–8.5 percent compared to SMS-only are the norm, with authentication journey latency reductions of 50–75 percent.

Conclusion

This is where mobile operator data shifts the approach. Rather than applying identical verification friction to every session, enterprises can use real-time network signals to make adaptive authentication decisions. Verify silently when conditions are right, step up when risk indicators appear, and block when fraud is detected.

Enterprise implementation of the offering makes those risk signals and authentication methods accessible through a composable API layer. The combination of Identity Insights for pre-verification intelligence, Verify for network-layer authentication, and Fraud Defender for channel protection delivers risk-proportionate authentication that’s in production at scale today.

The solution deploys with minimal changes to your existing Amazon Cognito user pool. Start with high-risk journeys, measure impact, and expand. Vonage Verify API is available across over 700 MNOs in over 200 countries and territories, and the integration requires only three Lambda functions.

Next steps

Vonage is an AWS Partner. To learn more, visit the Vonage partner page.

The content and opinions in this post are those of the third-party author and AWS is not responsible for the content or accuracy of this post.


About the authors

Threat tactic spotlight: Subdomain takeover

Post Syndicated from Matt Gurr original https://aws.amazon.com/blogs/security/threat-tactic-spotlight-subdomain-takeover/

In this blog post you’ll learn how to detect and prevent subdomain takeover – a tactic where threat actors exploit dangling DNS records to redirect traffic to attacker-controlled resources. We’ll explain the issue, how the situation arises, and how you can use various AWS features and services to help mitigate the impact of this tactic.

Under the shared responsibility model, securing configurations in the cloud is your responsibility. AWS supports you through strong defaults, guidance in the Security Pillar of the Well-Architected Framework, and security services to help you meet that responsibility. The AWS Customer Incident Response Team (AWS CIRT) also monitors for new and trending tactics that threat actors use to exploit specific customer configurations, so that you can make informed design decisions and improve your response plans.

AWS CIRT has observed threat actors actively scanning for public DNS CNAME records that point to resources that no longer exist, looking for subdomain takeover opportunities.

Note: The subdomain takeover tactic does not leverage vulnerabilities of AWS services. It exploits a dangling DNS record to redirect traffic to an attacker-controlled resource.

Quick DNS Primer

CNAME Records: A CNAME (Canonical Name) record is a DNS entry that points one domain name to another. For example, api.example.com can be configured to point to api.example.s3-website-us-east-1.amazonaws.com. This feature of DNS enables users to configure a memorable, human-friendly domain name while the actual resource lives at a longer, machine-generated AWS hostname. A security issue emerges when the target resource is deleted but the CNAME record pointing to it remains – creating a “dangling” record.

Dangling Records: When a resource (like an S3 bucket) is deleted but the DNS record pointing to it is left behind, that DNS record becomes “dangling”, pointing to a resource that no longer exists. For resources in globally shared namespaces, threat actors can potentially reclaim the name of your deleted resource and serve malicious content through your DNS record.

What is subdomain takeover?

A subdomain is a prefix added to a domain that allows you to organize access to your resources. A subdomain takeover occurs when you delete the underlying resource and a threat actor creates a new resource with the same name to take advantage of the DNS records still pointing to it.

A subdomain takeover is possible when a CNAME record points to an AWS resource that uses a globally shared DNS namespace where the resource name can be chosen by any AWS customer. The following AWS resources meet these criteria:

Amazon S3 (global namespace): Bucket names like mybucket.s3.amazonaws.com are globally unique and can be claimed by any account if the bucket is deleted. Note: S3 buckets created with account regional namespaces (launched March 2026) are scoped to your account and are not subject to this issue.

Amazon CloudFront: Distribution domain names like d111111abcdef8.cloudfront.net are assigned by AWS and cannot be chosen by an attacker. However, if you delete a distribution and another customer creates one that happens to receive the same domain name, a dangling CNAME could resolve to their content.

AWS Elastic Beanstalk: Environment names like myapp.elasticbeanstalk.com are globally unique and can be claimed by any account if the environment is terminated.

Resources like Amazon VPC, Amazon EC2 instances, or private hosted zones are not subject to this tactic because they do not expose globally claimable DNS namespaces.

MITRE ATT&CK classifies this technique under T1584.001: Compromise Infrastructure – Domains.

Analyzing an example scenario

Consider the following scenario:

You create a DNS CNAME record pointing to your S3 website endpoint. The subdomain subdomain.example.com now resolves to subdomain.example.s3-website-us-east-1.amazonaws.com, which serves content from the S3 bucket named subdomain.example. If your team deletes the bucket and forgets to delete the DNS record, users that navigate to the site will see an error stating that the bucket doesn’t exist. However, at this point, if a threat actor sees this error and moves in to claim the bucket name, they will be able to set up their own site that users will see when they navigate to the subdomain.example.com site.

Figure 1 shows an S3 bucket named subdomain.example (a globally unique bucket name) configured to host a static website, with the S3 website endpoint subdomain.example.s3-website-us-east-1.amazonaws.com.

Figure 1: S3 bucket configured as a static website

Figure 1: S3 bucket configured as a static website

As shown in Figure 2, we use Amazon Route 53 to create a CNAME record to resolve to our Amazon domain name; to give users a friendly name and so they do not have to remember the long S3 website name in URLs.

Figure 2: DNS Resolver configured with CNAME record pointing to origin bucket

Figure 2: DNS Resolver configured with CNAME record pointing to origin bucket

The customer’s AWS administrator decides to stop serving content from the S3 bucket and deletes it, as shown in Figure 3.

Figure 3: Resource deleted without removing the CNAME record

Figure 3: Resource deleted without removing the CNAME record

With the S3 bucket deleted and the CNAME record still in place, the DNS record is now dangling. A threat actor identifies this situation and creates a new S3 bucket with the same global name subdomain.example in an AWS account that the threat actor controls, as shown in Figure 4. The threat actor can now serve content from this new bucket, including potentially malicious content. End users remain unaware of this switch and continue to access subdomain.example.com, trusting the content because it appears to originate from a URL they recognize.

Figure 4: Subdomain takeover happens

Figure 4: Subdomain takeover happens

Potential impacts of a sub-domain takeover

Consider these potential impacts:

Reputation risk: There is a potential risk to your organization’s reputation, because you don’t control the content being served from the threat actor’s site that your DNS record points to.

Potential exposure to phishing campaigns: Users within your organization might have the subdomain bookmarked in their browser, not knowing the resource is no longer available, then unsuspectingly navigate to the site that now hosts malware or is used to phish user credentials.

Blocking: If the subdomain is flagged by security vendors for malicious activity, it could impact your business operations.

Financial loss: Subdomain takeover incidents can result in a financial impact due to the potential disruption to service delivery as you deal with the event.

Proactive detection

AWS Config for proactive detection

For proactive detection, you can use AWS Config to continuously monitor your Route 53 CNAME records and verify that the target resources exist in your account.

Prerequisite: This approach requires AWS Config recorder to be enabled for the resource types you want to monitor (S3 buckets, CloudFront distributions, Elastic Beanstalk environments). If Config isn’t recording a resource type, it won’t appear in the inventory check. For more information, see Setting up AWS Config with the console.

Why use AWS Config inventory instead of DNS resolution checks?

A common approach is to check whether a CNAME resolves to a valid endpoint. However, this method has a critical flaw: if an attacker has already claimed the resource, DNS resolution will succeed – to their resource, not yours. You would have no indication that you don’t own what’s responding.

By querying AWS Config’s recorded configuration items, you’re checking whether the resource exists in your account inventory, not just whether something responds at that DNS name. This approach correctly identifies dangling CNAMEs even after a takeover has occurred.

Implementation approach:

Account-level vs. organization-level scope

The reference implementation queries AWS Config inventory within a single account. This means that if a CNAME record in Account A points to a resource that legitimately exists in Account B within the same AWS organization, the rule will flag it as NON_COMPLIANT.

For organizations that share resources across accounts, you can modify the solution to use an AWS Config Aggregator, which queries resource inventory across all accounts in your organization. This is similar to how IAM Access Analyzer supports both account-level and organization-level scopes. To use this approach, you need an organization-level Config Aggregator already configured, and the Lambda function’s IAM role needs the config:SelectAggregateResourceConfig permission.

We recommend starting with account-level scope for simplicity, then expanding to organization-level if your environment includes cross-account resource sharing.

The main idea is to create a custom AWS Config rule that queries your Route 53 hosted zones for CNAME records, then parses each CNAME target to determine whether it points to a known AWS resource pattern such as S3, CloudFront, or Elastic Beanstalk. For each match, the rule cross-references the target against your AWS Config inventory to verify that the resource actually exists in your account. If the resource isn’t found, the rule marks the CNAME record as NON_COMPLIANT, surfacing it for review.

The Config rule should focus on known AWS resource patterns:

  • S3: *.s3.amazonaws.com, *.s3-website-<region>.amazonaws.com
  • CloudFront: *.cloudfront.net
  • Elastic Beanstalk: *.elasticbeanstalk.com

Note: CNAME records pointing to external third-party services are outside the scope of this detection mechanism, as those resources won’t appear in your AWS Config inventory.

NON_COMPLIANT findings from your Config rule can be routed to AWS Security Hub for centralized visibility, or trigger SNS notifications to alert your security team.

Figure 5: Dangling DNS Detection Solution

Figure 5: Dangling DNS Detection Solution

Reference implementation:

We’ve published a complete implementation of this detection approach as an open-source solution. The solution deploys a Lambda function that discovers CNAME records across all your Route 53 hosted zones and uses pattern matching to identify targets pointing to S3, CloudFront, and Elastic Beanstalk. It then queries your AWS Config inventory to verify whether each target resource still exists in your account. When a dangling record is detected, the solution generates a HIGH severity finding in Security Hub and can optionally send SNS notifications to alert your security team. A CloudWatch metrics dashboard is also included for ongoing compliance tracking.

Deployment:

# Clone the repository
git clone https://github.com/aws-samples/sample-dangling-dns-detection
cd sample-dangling-dns-detection

# Build the Lambda deployment package
./scripts/package.sh

# Upload to S3
aws s3 cp dist/dangling-dns-detection.zip s3://YOUR_BUCKET/

# Deploy the CloudFormation stack
aws cloudformation deploy \
  --template-file infrastructure/template.yaml \
  --stack-name dangling-dns-detection \
  --parameter-overrides \
      LambdaCodeS3Bucket=YOUR_BUCKET \
      EvaluationFrequency=TwentyFour_Hours \
  --capabilities CAPABILITY_NAMED_IAM

The stack creates an AWS Config custom rule that runs on your specified schedule (default: every 24 hours), evaluating all CNAME records and reporting compliance status.

Mitigating the effects

Mitigating subdomain takeover requires both preventive procedures and responsive capabilities.

Prevention: Standard operating procedure

The most effective mitigation is a standard operating procedure for resource deprovisioning that ensures DNS records are removed before the underlying resource:

  1. Within your DNS zone, delete the CNAME record that points to the fully qualified domain name (FQDN) of the resource that you plan to deprovision.
  2. Wait for the DNS TTL to expire before deleting the resource. DNS resolvers cache records for the duration of the TTL (for example, a TTL of 3600 means resolvers may serve the old record for up to one hour). If you delete the resource before the TTL expires, a threat actor could claim the resource name while cached CNAME entries are still directing traffic to it.
  3. Deprovision the resource that you no longer want to use.
  4. Run a DNS check of the CNAME record that you removed to verify that the resource is no longer resolving.

Key principle: Always delete DNS first, wait for the TTL to expire, then delete the resource. This order eliminates the window where a dangling record could be exploited.

Prevention: S3 account regional namespaces

As mentioned earlier, AWS introduced account regional namespaces for Amazon S3 general purpose buckets in March 2026. While this is a meaningful step toward mitigating the S3-specific takeover vector, there are important operational limitations to be aware of:

Existing buckets are unaffected. Buckets already created in the global namespace cannot be migrated to an account regional namespace. The bucket names remain globally unique and claimable by anyone if the bucket is deleted.

Global namespace is still the default. When creating a new bucket through the console, CLI, or SDK, the global namespace remains the default selection. Users who aren’t aware of the new option will continue creating globally-scoped buckets.

Existing IaC templates require updates. Existing infrastructure-as-code templates (CloudFormation, CDK, Terraform) that don’t explicitly opt in to the account regional namespace will continue provisioning buckets in the global namespace. For CloudFormation, this means setting the BucketNamespace property to account-regional. For other IaC tools, consult their documentation for the equivalent configuration. Organizations need to audit and update their templates to opt in.

For these reasons, the dangling DNS detection approach described in this post remains critical – particularly for organizations with existing S3 infrastructure, and for CloudFront, and Elastic Beanstalk resources where no equivalent namespace scoping exists.

Response: Notification and remediation

When a dangling DNS record is detected, the reference solution described in the Detection section automatically creates a HIGH severity finding in AWS Security Hub and reports the CNAME record as NON_COMPLIANT in AWS Config. If you provide an SNS topic ARN during deployment, the solution also sends notifications to alert your security or operations team via email, Slack, or other channels. For production environments, consider a human-in-the-loop workflow where these notifications are reviewed by a team member who approves the DNS record deletion before it’s executed. This prevents accidental deletion of legitimate records during transient issues.

The reference solution also includes a CloudWatch dashboard for tracking compliance status and evaluation metrics over time, giving your team ongoing visibility into DNS health across your hosted zones.

Note: Fully automated remediation (auto-deleting DNS records) carries risk – a false positive could disrupt legitimate services. We recommend starting with detection and notification, then evaluating automation based on your detection accuracy and operational maturity.

Conclusion

Subdomain takeover is a preventable misconfiguration that can have significant impact on your organization. A layered defense approach provides the best protection:

Prevention: Implement a standard operating procedure that deletes DNS records before deprovisioning the underlying resource.

Detection: Use AWS Config custom rules to proactively identify CNAME records pointing to resources that no longer exist in your account.

Response: Configure notifications through SNS or Security Hub so your team can respond quickly when dangling records are detected.

Monitoring: Maintain ongoing visibility through CloudWatch dashboards to track DNS health and compliance status.

The key insight is that good DNS hygiene – knowing when your CNAME records point to a nonexistent resource – is your first line of defense. Automated detection through AWS Config provides a safety net when operational procedures fail. And if you detect an issue, having a playbook ready to enact your response can lower the impact and your mean time to recovery.

If you have feedback about this post, submit comments in the Comments section below.


Matt Gurr

Matthew Gurr

Matthew is the Senior Incident Response lead in the Asia-Pacific region for the AWS Customer Incident Response Team (AWS CIRT). He has a passion for helping customers proactively prepare for a security event. In his spare time, he enjoys cycling, music, and reading.

Luis Pastor

Luis Pastor

Luis is a Senior Security Solutions Architect at AWS leading the Infrastructure Security and Compliance Technical Field Communities. He drives security architecture for enterprise customers across financial services, healthcare, and retail, specializing in cloud security transformation and regulatory compliance frameworks. Before AWS, Luis architected security solutions in hybrid cloud environments.

Geoff Sweet

Geoff Sweet

Geoff has been in industry since the late 1990s. He began his career in electrical engineering. Starting in IT during the dot-com boom, he has held a variety of diverse roles, such as systems architect, network architect, and, for the past several years, security architect. Geoff specializes in infrastructure security.

Ariam Michael

Ariam Michael

Ariam is a Solutions Architect at AWS. She has supported various customers in the Worldwide Public Sector, specifically SLG and Federal Civilian customers. She is passionate about security, specifically Data Protection helping customers implement encryption and best practices.

How Samsung achieved real-time pricing with AWS Lambda Response Streaming

Post Syndicated from Vijay Naik original https://aws.amazon.com/blogs/architecture/how-samsung-achieved-real-time-pricing-with-aws-lambda-response-streaming/

This post is co-authored with Sathish Kumar and Christopher Chan from Samsung ecommerce.

In high-traffic ecommerce, achieving real-time pricing is critical to prevent price inconsistency. Pricing inconsistency creates cart shock and erodes trust. This isn’t broken software, it’s a symptom of architectural latency that you can address using AWS Lambda Response Streaming and Amazon CloudFront for systems aggregating data from multiple backend sources.

In this post, we walk through the legacy architecture challenges, the stateless streaming solution, key implementation patterns, and performance results—a pattern you can apply if you’re building high-traffic APIs that aggregate data from multiple backend sources.

Samsung.com is Samsung’s primary direct-to-consumer channel, selling smartphones, TVs, appliances, and accessories, each with multiple variants, offers, and regional pricing. This complexity makes real-time price accuracy especially important.

Samsung’s All Deals and Product Finder pages showcase these products during high-traffic events like Black Friday. To maintain low latency for these high-density Product Listing Pages (PLPs) and comparison tables, the legacy infrastructure relied on asynchronous caching, which introduced a desynchronization gap where the cached price drifted from the authoritative pricing engine.

Problem: Legacy middleware caching created a 1-hour desynchronization gap between the authoritative pricing engine and customer-facing pages.

Our approach: We dismantled the stateful Data Aggregation (DA) architecture and built a real-time Bulk Arbitration Engine (a stateless orchestration layer that queries the Pricing Engine directly at request time) using AWS Lambda Response Streaming and Amazon CloudFront edge caching.

Challenge: The Data Aggregation trap

When product listing pages need to display pricing for over 30 item combinations simultaneously, the latency of calling the Pricing Engine for each item combination individually becomes untenable. To solve this, we built a backend for frontend (BFF) service to do a “Data Aggregation. This DA service was designed to decouple the frontend from the heavy Pricing Engine.

It relied on a scheduled Cron Worker that ran hourly to fetch the entire product catalog. The worker would then precompute prices for every possible permutation of products and store them in a local cache.

While this improved read speeds, it created two significant failures:

1. The Permutation Explosion – The DA service had to precompute every combination just in case a customer viewed it.

  • The Math: 30 products × (Variants × Offers × Add-ons) = Thousands of records per page
  • Storage Impact: Cache grew exponentially with each new product variant added
  • Waste: Most precomputed combinations were never requested

2. The Synchronization Lag – Because the Cron job ran only once per hour, price changes (for example, flash sales) lagged significantly. Customers continued to see old prices until the next scheduled sync.

  • Business Impact: Flash sales showed incorrect old pricing until the next run time
  • Customer Trust: Cart shock when checkout price differed from product page price
  • Competitive Disadvantage: Competitors with real-time pricing gained market share

Legacy Data Aggregation architecture

Architecture diagram showing the legacy Data Aggregation layer between the Pricing Engine and CloudFront CDN.

Architecture diagram showing the legacy Data Aggregation layer between the Pricing Engine and CloudFront CDN

Figure 1: Legacy Data Aggregation (DA) Architecture The legacy system relied on a scheduled Cron job, creating a distinct “Desynchronization Layer” between the Authority (Pricing) and the Customer. Precomputation of all product permutations consumed significant storage and compute resources.

The solution: Stateless streaming architecture

Intermediate layers storing data will eventually diverge from the source, so we collaborated with our AWS Technical Account Manager (TAM) and service teams to architect a new solution: the Bulk Arbitration Engine, a stateless orchestration layer that queries the Pricing Engine directly at request time.

The new architecture follows a Pass-Through pattern:

1. Client Request: The browser requests prices for 30 specific SKUs using a single HTTP GET request.

2. Streaming Orchestration: An AWS Lambda function fans out these 30 requests to the Pricing Engine in parallel.

3. Immediate Response: As the Pricing Engine returns data, the Lambda streams it immediately to the client without buffering.

Why Lambda Response Streaming?

We evaluated several alternatives before settling on this approach:

  • Traditional request-response pattern (buffered) – A standard Lambda invocation buffers the full response before returning it to the client, which negates the latency benefit of parallel fan-out. For 30 concurrent SKU lookups, this added seconds of wait time.
  • EC2 with improved caching – This was the legacy approach. Caching layers will eventually drift from the source of truth, which was the core problem we needed to solve.
  • Lambda Response Streaming – This was the only option that let us fan out requests in parallel, stream results as they arrived (reducing time-to-first-byte), and remain fully stateless with no intermediate cache to maintain or invalidate.

New stateless streaming architecture

New stateless Lambda Response Streaming architecture with CloudFront caching layer directly connected to Lambda function, which streams real-time responses from Pricing Engine without intermediate buffering. The diagram shows customer GET request to CloudFront, cache hit/miss routing decision, Lambda orchestration of parallel SKU lookups, and streaming response back through CloudFront edge.

Architecture diagram showing the stateless streaming solution with CloudFront connected directly to Lambda.

Architecture diagram showing the stateless streaming solution with CloudFront connected directly to Lambda

Figure 2: Stateless Streaming Architecture The new architecture eliminates the middleware cache. A high-performance stream connects the user directly to the pricing source of truth. CloudFront edge locations cache the response for 95% of traffic, while remaining requests go directly to Lambda for real-time pricing.

Implementation walkthrough

Transitioning to this new architecture required solving two specific technical constraints regarding CDN behavior and cold starts. We implemented the solution in three steps.

Step 1: Implementing the streaming handler

The core of our solution is the Node.js Lambda handler wrapped in awslambda.streamifyResponse(). This allows us to pipe data through a transformation and compression stream directly to the client as it becomes available.

We used a custom NDJSONTransform to convert pricing objects into newline-delimited JSON (NDJSON), allowing the browser to parse and render each price as it arrives rather than waiting for the complete response.

// Lambda Handler with Response Streaming
// File: lambda-handler.js

import * as awslambda from "aws-lambda";
import * as zlib from "zlib";
import { pipeline } from "stream/promises";
import { NDJSONTransform } from "./transforms/ndjson-transform.js";

// Constants
const PROCESSING_MODE = process.env.PROCESSING_MODE || "MODE_QUERYSTRING";
const MODE_QUERYSTRING = "MODE_QUERYSTRING";

// The Handler MUST be wrapped in streamifyResponse() to enable streaming
export const handler = awslambda.streamifyResponse(
  async (event, responseStream, _context) => {
    try {
      if (PROCESSING_MODE === MODE_QUERYSTRING) {
        // Set response metadata with status code and headers
        const httpResponseMetadata = {
          statusCode: 200,
          headers: {
            "Content-Type": "application/x-ndjson",
            "Content-Encoding": "gzip",
            "Cache-Control": "public, max-age=300", // 5 min cache
            "X-Custom-Header": "lambda-streaming",
          },
        };

        responseStream = awslambda.HttpResponseStream.from(
          responseStream,
          httpResponseMetadata
        );

        const ndjsonTransform = new NDJSONTransform();

        // Create gzip stream with fast compression level (Z_BEST_SPEED = Level 1)
        // Level 1 prioritizes speed over compression ratio for real-time responses
        const gzip = zlib.createGzip({
          level: zlib.constants.Z_BEST_SPEED,
        });

        // Process the request, writing to the gzip stream
        await processRequestUsingQueryString(event, ndjsonTransform, _context);

        // Pipeline: Transform → Compress → Send
        await pipeline(ndjsonTransform, gzip, responseStream);
      }

      // ... error handling
    } catch (error) {
      console.error("Lambda streaming error:", error);
      responseStream.destroy();
    } finally {
      await flushMetrics().catch(console.error);
    }
  }
);

Helper function to fan-out the requests in parallel:

// Process request: fan out SKU lookups in parallel
async function processRequestUsingQueryString(event, ndjsonTransform, context) {
  try {
    // Parse query string to extract SKU list
    const queryString = event.rawQueryString || "";
    const skus = parseCompressedQueryString(queryString);

    // Fetch pricing in parallel using Promise.all
    const pricingPromises = skus.map((sku) =>
      fetchPricingForSKU(sku).catch((err) => ({
        sku: sku.id,
        error: err.message,
      }))
    );

    const pricingResults = await Promise.all(pricingPromises);

    // Emit each result as a separate NDJSON line
    for (const result of pricingResults) {
      ndjsonTransform.write(result);
    }

    ndjsonTransform.end();
  } catch (error) {
    ndjsonTransform.destroy(error);
  }
}

The handler also uses helper functions for parsing the compressed query string (parseCompressedQueryString), fetching individual SKU prices with connection pooling (fetchPricingForSKU), and flushing metrics to Amazon CloudWatch (flushMetrics).

Key implementation details:

  • awslambda.streamifyResponse() wraps the handler so it streams data in real time instead of waiting for the full response from the pricing engine.
  • NDJSONTransform converts objects to newline-delimited JSON (one object per line)
  • GZIP (GNU zip) compression with Z_BEST_SPEED (Level 1) prioritizes speed over compression ratio
  • pipeline() handles error propagation and stream cleanup
  • Response headers include Cache-Control for CloudFront caching

Step 2: Compressing the request data into a GET request

We needed to send complex request data (30 SKUs, context metadata) to the API.

Constraint: CloudFront and standard HTTP specs treat POST requests as non-idempotent, meaning they are not cacheable by default.

Our approach: We developed a dense, compressed query string format to fit the complex request data into a standard GET request. Format: g=group1(p=SKU-A:1:p=SKU-B:2)…

This allowed us to strictly use GET requests, keeping the request URI within standard length limits (~800 bytes) while carrying the same data as a 3-4KB JSON body.

Client-Side Code: Building the Compressed Query String

// Client-side: Building the compressed query string format
// File: pricing-client.js

/**
 * Builds a compressed query string for bulk pricing requests
 * Format: g=group1(p=SKU-A:1:p=SKU-B:2:p=SKU-C:3)
 * @param {Array} skus - Array of SKU objects with { id, variant }
 * @param {Object} context - Customer context { customerId, region, sessionId }
 * @returns {string} Compressed query string
 */
function buildPricingQueryString(skus, context = {}) {
  if (!skus || skus.length === 0) {
    throw new Error("SKUs array cannot be empty");
  }

  if (skus.length > 30) {
    throw new Error("Maximum 30 SKUs per request. Split into multiple batches.");
  }

  // Build SKU portion: p=SKU-001:1:p=SKU-002:2
  const skuParts = skus
    .map((sku) => {
      const variant = sku.variant || 1;
      return `p=${sku.id}:${variant}`;
    })
    .join(":");

  // Build context portion (optional)
  let contextPart = "";
  if (context && Object.keys(context).length > 0) {
    const contextStr = Object.entries(context)
      .map(([key, value]) => `${key}=${value}`)
      .join(":");
    contextPart = `:c=${contextStr}`;
  }

  // Final format: g=group1(p=SKU-A:1:p=SKU-B:2:c=customerId=123:region=US-EAST-1)
  return `g=group1(${skuParts}${contextPart})`;
}

/**
 * Fetches pricing data with streaming NDJSON response parsing
 * Core pattern: read chunks, split by newlines, parse each line as JSON
 */
async function fetchPricingStream(skus, options = {}) {
  const queryString = buildPricingQueryString(skus);
  const url = `${options.baseUrl}?${queryString}`;
  const response = await fetch(url, {
    method: "GET",
    headers: { Accept: "application/x-ndjson" },
  });

  // Stream the response using the ReadableStream API
  const reader = response.body.getReader();
  const decoder = new TextDecoder();
  const pricingData = [];
  let buffer = "";

  while (true) {
    const { done, value } = await reader.read();
    if (done) break;

    // Decode chunk and append to buffer
    buffer += decoder.decode(value, { stream: true });

    // Split by newlines (NDJSON format: one JSON object per line)
    const lines = buffer.split("\n");

    // Keep the last incomplete line in buffer
    buffer = lines.pop() || "";

    // Parse each complete line as a JSON object
    for (const line of lines) {
      if (line.trim()) {
        const pricingObject = JSON.parse(line);
        pricingData.push(pricingObject);

        // Optional: update UI immediately as each price arrives
        if (options.onChunk) {
          options.onChunk(pricingObject);
        }
      }
    }
  }

  reader.releaseLock();
  return pricingData;
}

On page load, the client calls fetchPricingStream with up to 30 SKUs and an onChunk callback that updates each product’s DOM (Document Object Model) element as pricing chunks arrive. Helper functions handle updating individual price elements, displaying variant information, and gracefully degrading with a user-friendly message if pricing is temporarily unavailable.

Step 3: Configuring CloudFront for uncacheable requests

To allow CloudFront to cache these complex GET requests effectively, we configured a precise Cache Policy that includes all query strings and specific headers.

# Terraform: CloudFront Cache Policy Configuration
# File: cloudfront-cache-policy.tf

resource "aws_cloudfront_cache_policy" "pricing-cache-policy" {
  name = "${var.lambda_function_name}-cache-policy"

  # TTL Configuration
  default_ttl = 300  # 5 minutes
  max_ttl     = 1800 # 30 minutes
  min_ttl     = 300   # 5 minute

  parameters_in_cache_key_and_forwarded_to_origin {
    # Don't cache based on cookies (we don't use them)
    cookies_config {
      cookie_behavior = "none"
    }

    # Allowlist specific headers for cache key
    headers_config {
      header_behavior = "whitelist"
      headers {
        items = [
          "x-ecom-pricing-1",   # Custom headers (anonymized)
          "x-ecom-pricing-2",  
          "x-ecom-pricing-3"    
        ]
      }
    }

    # Include query strings in cache key
    # This verifies different SKU combinations have separate cache entries
    query_strings_config {
      query_string_behavior = "all"
    }

    # Enable automatic GZIP compression
    enable_accept_encoding_gzip = true
  }
}

# CloudFront Origin Request Policy (forward headers to Lambda)
resource "aws_cloudfront_origin_request_policy" "pricing-origin-policy" {
  name = "${var.lambda_function_name}-origin-policy"

  headers_config {
    header_behavior = "whitelist"
    headers {
      items = [
        "x-ecom-pricing-1",
        "x-ecom-pricing-2",
        "x-ecom-pricing-3"
      ]
    }
  }

  query_strings_config {
    query_string_behavior = "all"
  }

  cookies_config {
    cookie_behavior = "none"
  }
}

The CloudFront distribution itself is configured with HTTPS-only viewer protocol, the cache policy and origin request policy as shown in the preceding section, and points to the Lambda as its origin through HTTPS.

Cache policy highlights:

  • 5-minute default TTL balances freshness and cache efficiency
  • Query strings included in cache key (different SKU combos = separate cache entries)
  • Header allowlisting allows custom pricing variants
  • Automatic GZIP compression reduces bandwidth
  • 5–30 minute TTL range provides flexibility for different content

Performance optimization results

We optimized the system through four distinct phases, testing each configuration with K6 load test scripts (500 concurrent users, 30 items per request) to simulate high-traffic events like Black Friday.

Phase 1: The baseline (Global VPN)

We tested our initial proof-of-concept with the default network configuration, where all outbound traffic (including requests to AWS services like Lambda) was routed through a global VPN, forcing traffic onto the public network and back into the AWS backbone, adding unnecessary network hops and delays. The Lambda used a standard buffered response with no compression. The results were suboptimal (4,500ms P90) because connection overhead dominated the request.

  • DNS resolution: approximately 50 ms
  • TCP handshake: approximately 100 ms
  • TLS negotiation: approximately 150 ms
  • Total connection overhead: approximately 300 ms per call

This overhead created a massive bottleneck for latency before business logic even ran.

Phase 2: Amazon VPC Peering and warm starts

To remove the network penalty, we acted on two fronts:

  • First: Moved the Lambda inside an Amazon Virtual Private Cloud (Amazon VPC) peered directly to the pricing origin, cutting DNS and TLS overhead to near zero for internal calls.
  • Second: Enabled Provisioned Concurrency for Lambda to remove the 500–1000 ms cold start latency.

With these changes, P90 latency dropped to 1,000 ms, a 4.5x improvement, but still not real-time enough.

Phase 3: HTTP/2 and GZIP compression

The remaining bottleneck was the sheer size of the data transfer. We targeted two optimizations:

  • HTTP/2 Multiplexing: Enabled HTTP/2 multiplexing to reuse a single TCP connection for the 30 parallel SKU lookups, saving seconds of cumulative handshake time.
  • GZIP Compression: Applied GZIP compression (Level 1 / Z_BEST_SPEED), which reduced the response size by 76 percent (170KB → 40KB).

These two optimizations brought P90 latency down to 218 ms.

Phase 4: Production (edge caching)

In the final phase, we layered CloudFront edge caching on top of the optimized Lambda. Because we had successfully converted our request data to a GET request (Step 2), we could now cache the computed prices for 95 percent of incoming traffic.The final P90 latency landed at 50 ms.In practice, the 95 percent cache hit ratio means only 1 in 20 requests actually invokes the Lambda function; the rest are served directly from CloudFront edge locations closest to the customer. During peak events like Black Friday, this translates to millions of requests served at edge speed without touching the origin, keeping both latency and compute costs minimal.

Performance metrics table

Metric Phase 1 (Baseline) Phase 2 (VPC) Phase 3 (HTTP/2) Phase 4 (Production)
P50 Latency 1,670 ms 501 ms 176 ms 35 ms
P90 Latency 4,500 ms 1,000 ms 218 ms 50 ms
P99 Latency 5,100 ms 2,400 ms 500 ms 150 ms
Cache Hit Ratio <1% <1% <1% 95%
Response Size 170 KB 170 KB 40 KB 40 KB
Concurrent Users 500 500 500 500
P90 Improvement vs Baseline 1x 4.5x 20x 90x

The following chart shows P90 latency improvements across each optimization phase.

Latency improvements across four optimization phases

Latency improvements across four optimization phases.

K6 load test configuration:

// A sample K6 load test script
import http from 'k6/http';
import { check } from 'k6';

export let options = {
  stages: [
    { duration: '2m', target: 100 },  // Ramp up
    { duration: '5m', target: 500 },  // Stay at 500 concurrent users
    { duration: '2m', target: 0 },    // Ramp down
  ],
  thresholds: {
    http_req_duration: ['p(90)<100', 'p(99)<500'], // P90 < 100ms, P99 < 500ms
  },
};

export default function () {
  const url = 'https://api.example.com/pricing?g=group1(p=SKU-001:1:p=SKU-002:2:...)';
  const res = http.get(url);
  
  check(res, {
    'status is 200': (r) => r.status === 200,
    'response has content': (r) => r.body.length > 0,
  });
}

Resilience, scale, and security considerations

Beyond latency, we designed the system to handle failure gracefully, scale under load, and protect data in transit.

Batching limits

The 30-item limit per request is intentional. If a page requires more (for example, 50 items), the client logic splits them into multiple parallel batches.–We chose 30 because of the following:

  • Lambda execution time under 5 seconds
  • Prevents timeout issues during high latency
  • Balances parallel requests vs. Lambda concurrency limits
  • Typical product listing pages show 20–30 items
async function fetchLargePricingBatch(skus) {
  const BATCH_SIZE = 30;
  const batches = [];

  // Split into 30-item chunks
  for (let i = 0; i < skus.length; i += BATCH_SIZE) {
    batches.push(skus.slice(i, i + BATCH_SIZE));
  }

  // Fetch all batches in parallel
  const results = await Promise.all(
    batches.map((batch) =>
      fetchPricingStream(batch, { timeout: 30000 })
    )
  );

  // Flatten results
  return results.flat();
}

Partial failures

The streaming architecture is resilient. If pricing for one item fails, the stream doesn’t crash; it continues processing the remaining items, so the user still sees a mostly complete page.

Partial failure handling:

async function processRequestUsingQueryString(event, ndjsonTransform, context) {
  const skus = parseCompressedQueryString(event.rawQueryString);

  for (const sku of skus) {
    try {
      const pricing = await fetchPricingForSKU(sku);
      ndjsonTransform.write(pricing);
    } catch (error) {
      // Emit error object but continue processing other SKUs
      ndjsonTransform.write({
        sku: sku.id,
        variant: sku.variant,
        error: error.message,
        timestamp: new Date().toISOString(),
      });
    }
  }

  ndjsonTransform.end();
}

Data protection

  • While constructing the query string on the client exposes the request structure, this data (SKUs, variants) is already public. The actual pricing logic and business rules remain securely protected within the Pricing Engine.
  • Data in transit encrypted with TLS 1.3.
  • Amazon VPC endpoint connection to pricing engine (no internet exposure).
  • No sensitive data logged (PII, pricing algorithms excluded).
  • CloudTrail logs API calls for audit trail.

Conclusion

Stale pricing forces engineering teams to choose between freshness and scale. With the Data Aggregation pattern, we attempted to maintain both but compromised on data integrity due to the lag inherent in scheduled synchronization.By using AWS Lambda Response Streaming and Amazon CloudFront, we removed the need for a synchronization layer entirely. The result is a system that delivers the 50 ms latency required for a smooth user experience while supporting price consistency between the product page and checkout.

Beyond performance, this architecture significantly reduced operational footprint: compute fleet shrank from over 100 auto-scaled instances during peak events to only 5–10 Lambda functions, lowering maintenance and operational costs. This outcome was the result of close collaboration between Samsung’s ecommerce engineering team, our AWS Technical Account Manager (TAM), and the Lambda and CloudFront service teams, who helped architect the solution, review design decisions, and guide Samsung through production readiness. This technique applies to similar high-traffic data aggregation scenarios: product catalogs, inventory systems, recommendation engines, or services that combine multiple backend responses in real-time.

To get started, identify your highest-latency aggregation endpoints, evaluate whether your request data can be converted to cacheable GET requests and implement Lambda Response Streaming for a single endpoint before migrating your full API

Resources: – AWS Lambda Response Streaming documentation – Lambda Response Streaming tutorial – Amazon CloudFront Developer Guide – CloudFront cache policies

Learn more

For more on the concepts and technologies discussed in this post:


About the authors

Real-time CDC from Aurora PostgreSQL to Amazon S3 Tables using Debezium and Firehose

Post Syndicated from Chintan Agrawal original https://aws.amazon.com/blogs/big-data/real-time-cdc-from-aurora-postgresql-to-amazon-s3-tables-using-debezium-and-firehose/

Enterprises running transactional workloads on Amazon Aurora PostgreSQL-Compatible Edition (Aurora PostgreSQL) need their operational data available for analytics. However, analytical queries and cross-database joins compete for resources on OLTP-optimized clusters. Batch exports introduce latency, and when data spans multiple Aurora clusters, there’s no straightforward way to join datasets or run cross-domain analytics. Real-time change data capture (CDC) addresses this by streaming row-level changes into a separate analytics layer. However, most CDC approaches write append-only records that require downstream consumers to reconstruct current state from the change log.

In this post, we show you how to build a CDC pipeline that delivers query-ready Iceberg tables directly. The pipeline captures inserts, updates, and deletes from Aurora PostgreSQL and applies them as row-level operations in Amazon S3 Tables, a capability of Amazon Simple Storage Service (Amazon S3). The destination tables always reflect the current state of the source database. You use Debezium on Amazon MSK Connect for change capture and Amazon Managed Streaming for Apache Kafka (Amazon MSK) for streaming. You also use AWS Lambda to transform CDC events and resolve operation semantics, and Amazon Data Firehose to deliver records into Iceberg tables. You deploy the infrastructure using the AWS Cloud Development Kit (AWS CDK).

Apache Iceberg supports row-level updates, deletes, ACID transactions, schema evolution, and time travel natively. S3 Tables handles Iceberg snapshot management and compaction automatically. With AWS Lake Formation for access control, multiple teams can query the tables through Amazon Athena, Amazon Redshift, or Amazon SageMaker Unified Studio.

Solution overview

The following diagram shows the architecture of the CDC pipeline.

Figure 1. CDC pipeline architecture from Aurora PostgreSQL to Amazon S3 Tables.

Figure 1. CDC pipeline architecture from Aurora PostgreSQL to Amazon S3 Tables.

The pipeline uses six components:

  1. Aurora PostgreSQL to Debezium. Debezium runs on MSK Connect in your VPC and uses PostgreSQL’s native logical replication to stream row-level changes from the write-ahead log (WAL), with minimal impact on query performance.
  2. Debezium to Amazon MSK. The ByLogicalTableRouter SMT reroutes CDC events from multiple tables into a single topic (aurora.cdc.all-tables), retaining the source table name in each message.
  3. Amazon MSK to Firehose. Firehose connects to the MSK cluster using the IAM access control over AWS PrivateLink and continuously polls the topic for new messages.
  4. Firehose to Lambda. For each batch, Firehose invokes the Lambda function to decode the Kafka message, flatten the Debezium envelope, and set otfMetadata routing with the destination table and operation type.
  5. Firehose to S3 Tables. Firehose reads the otfMetadata, routes each record to the correct Iceberg table, and performs the appropriate row-level operation using configured unique keys (for example, order_id for orders). S3 Tables handles compaction and snapshot management automatically.
  6. Query and access control. After data lands in S3 Tables, you can query the Iceberg tables with Amazon Athena, Amazon Redshift, or Amazon SageMaker Unified Studio, with AWS Lake Formation managing fine-grained access control.

Firehose supports one MSK topic per delivery stream. The single-topic routing pattern uses a Debezium SMT to consolidate multiple tables into one topic, and a Lambda function to route records to the correct destination. With this, you can serve multiple tables through one Firehose stream, reducing cost and operational complexity.

Debezium event transformation

Debezium produces CDC events in an envelope structure containing both the previous and current state of a row, along with metadata about the source database, table, and operation type. However, Firehose expects records in a flattened JSON format with routing metadata that indicates the target table and operation type.

The Lambda function bridges this gap by performing three operations on each record:

  1. Decode. When Firehose uses Amazon MSK as a source, it delivers the Kafka message value as a base64-encoded string in the kafkaRecordValue field. The function base64-decodes this field to obtain the raw Debezium JSON payload.
  2. Flatten and extract. Pulls the row data from the Debezium envelope. For inserts and updates, the function uses the after field (the row after the change). For deletes, it uses the before field, because the after field is null when a row is removed.
  3. Route. Sets the otfMetadata block with destinationTableName (extracted from the Debezium source.table field) and operation (mapped from Debezium’s single-character codes to Firehose’s operation types).

The following table shows how Debezium operation codes map to Firehose Iceberg operations:

Debezium code Meaning Firehose operation
c Row created (insert) insert
u Row updated update
d Row deleted delete
r Snapshot read (initial load) insert

When Debezium starts with snapshot.mode=initial, it reads all existing rows and emits them as r (read) events. These represent rows that existed before CDC began, so they are mapped to insert to establish the baseline state in the destination tables.

For example, the function transforms this Debezium envelope:

{
"op": "c",
"before": null,
"after": {"order_id": 1, "customer_id": 1, "total_amount": 299.99},
"source": {"table": "orders", "db": "cdcdemo"}
}

Into a response record with routing metadata:

{
"recordId": "<original-record-id>",
"result": "Ok",
"kafkaRecordValue": "<base64-encoded flattened row JSON>",
"metadata": {
"otfMetadata": {
"destinationDatabaseName": "aurora_cdc",
"destinationTableName": "orders",
"operation": "insert"
}
}
}

The kafkaRecordValue contains the base64-encoded flattened row data (for example, {"order_id": 1, "customer_id": 1, "total_amount": 299.99}), and the otfMetadata block tells Firehose which table to write to and which operation to perform.

With this routing metadata, a single Firehose stream can write to multiple destination tables. For more information, see Route incoming records to different Iceberg tables.

Walkthrough

The following sections walk you through building the CDC pipeline end to end. Before you begin, complete the prerequisites.

Prerequisites

Before you begin, make sure you have the following:

Step 1: Enable CDC in Aurora PostgreSQL

PostgreSQL supports change data capture through its logical replication framework, which allows database changes to be streamed from the write-ahead log (WAL). Debezium uses this mechanism to continuously read row-level changes and publish them to Kafka topics.

To enable logical replication in Aurora PostgreSQL, configure a custom DB cluster parameter group:

  1. Create a custom parameter group and set the following parameter: rds.logical_replication = 1.
  2. Apply the parameter group to your Aurora cluster and reboot the cluster for the change to take effect.
  3. Connect to your Aurora PostgreSQL cluster and create the source tables:
CREATE TABLE public.orders (
    order_id SERIAL PRIMARY KEY,
    customer_id INTEGER,
    order_date VARCHAR(50),
    total_amount DECIMAL(12,2),
    status VARCHAR(50),
    created_at TIMESTAMP DEFAULT NOW(),
    updated_at TIMESTAMP DEFAULT NOW()
);
CREATE TABLE public.products (
    product_id SERIAL PRIMARY KEY,
    product_name VARCHAR(255),
    category VARCHAR(100),
    price DECIMAL(10,2),
    stock_quantity INTEGER,
    created_at TIMESTAMP DEFAULT NOW(),
    updated_at TIMESTAMP DEFAULT NOW()
);
  1. Create a publication that defines which tables are included in the change stream. Debezium automatically creates the logical replication slot when the connector starts for the first time, so you don’t need to create one manually.
CREATE PUBLICATION dbz_publication FOR TABLE public.orders, public.products;
  1. Verify the publication was created:
SELECT * FROM pg_publication WHERE pubname = 'dbz_publication';

You should see one row returned, confirming the publication is active.

Important: When the Debezium connector starts (Step 6), it creates a replication slot named debezium_slot. This slot retains WAL segments until consumed. If the connector is stopped for an extended period, WAL segments can accumulate and increase storage usage on the Aurora cluster. Monitor the ReplicationSlotDiskUsage Amazon CloudWatch metric for your Aurora cluster.

Step 2: Build and register the Debezium plugin

MSK Connect runs connectors using custom plugins that you upload to Amazon S3. In this step, you download the Debezium PostgreSQL connector, package it as a ZIP file, upload it to S3, and register it with MSK Connect.

First, create an S3 bucket for the plugin, or use an existing metadata management bucket:

aws s3 mb s3://<your-plugin-bucket> --region <your-region>

Download and package the Debezium connector:

DEBEZIUM_VERSION=2.7.3.Final
curl -LO "https://repo1.maven.org/maven2/io/debezium/debezium-connector-postgres/${DEBEZIUM_VERSION}/debezium-connector-postgres-${DEBEZIUM_VERSION}-plugin.tar.gz"
mkdir -p debezium-plugin
tar -xzf debezium-connector-postgres-${DEBEZIUM_VERSION}-plugin.tar.gz -C debezium-plugin/
cd debezium-plugin && zip -r ../debezium-postgres-connector.zip . && cd ..
aws s3 cp debezium-postgres-connector.zip s3://<your-plugin-bucket>/plugins/

Register the plugin with MSK Connect:

aws kafkaconnect create-custom-plugin \
    --custom-plugin-name debezium-postgres-connector \
    --content-type ZIP \
    --location "s3Location={bucketArn=arn:aws:s3:::<your-plugin-bucket>,fileKey=plugins/debezium-postgres-connector.zip}"

Create a worker configuration that tells MSK Connect to serialize Kafka messages as JSON without schemas:

aws kafkaconnect create-worker-configuration \
    --name debezium-worker-config \
    --properties-file-content "$(echo -n 'key.converter=org.apache.kafka.connect.json.JsonConverter
value.converter=org.apache.kafka.connect.json.JsonConverter
key.converter.schemas.enable=false
value.converter.schemas.enable=false' | base64)"

Note the customPluginArn and workerConfigurationArn from the output. You need these for the CDK configuration in the next step.

Note: The custom plugin and worker configuration are created through the AWS CLI because the Debezium connector JARs must be downloaded from the Debezium project and packaged manually. The remaining infrastructure is deployed using the AWS CDK in the following steps.

Step 3: Configure the CDK project

Clone the sample repository and install dependencies:

git clone https://github.com/aws-samples/sample-aurora-cdc-s3tables.git
cd sample-aurora-cdc-s3tables/cdk
npm install

Open cdk/lib/v2/config.ts and update the configuration values to match your environment:

export const CONFIG = {
account: '<your-account-id>',
region: '<your-region>',
// VPC - must match your Aurora cluster's VPC
vpcId: '<your-vpc-id>',
subnetIds: ['<subnet-1>', '<subnet-2>'],
auroraSecurityGroupId: '<aurora-security-group-id>',
// Aurora connection details
auroraEndpoint: '<aurora-cluster-endpoint>',
auroraPort: '5432',
auroraDbName: '<database-name>',
auroraUser: '<db-user>',
auroraSecretArn: '<secrets-manager-arn>',
// Debezium - use the ARNs from Step 2
debeziumPluginArn: '<customPluginArn-from-step-2>',
debeziumWorkerConfigArn: '<workerConfigurationArn-from-step-2>',
debeziumPluginBucket: '<your-plugin-bucket-name>',
debeziumTopicPrefix: 'aurora.cdc',
debeziumTables: 'public.orders,public.products',
// S3 Tables - the table bucket name must be globally unique
s3TablesBucketName: '<your-table-bucket-name>',
s3TablesNamespace: 'aurora_cdc',
tables: ['orders', 'products'],
tableKeys: { orders: 'order_id', products: 'product_id' },
// Firehose - general purpose S3 bucket for failed record backup
firehoseBackupBucket: '<your-backup-bucket-name>',
};

Key configuration notes:

  • auroraSecurityGroupId. The security group attached to your Aurora cluster. The CDK creates an MSK security group with ingress rules allowing traffic from this security group, and a reverse rule allowing MSK Connect workers to reach Aurora on port 5432.
  • tableKeys. The primary key column for each table. Firehose uses these to match incoming records against existing rows for update and delete operations in the Iceberg tables.
  • s3TablesBucketName. The name for your S3 table bucket. Table bucket names must be unique for your account in the chosen Region.

Step 4: Deploy the CDK stacks

Deploy all six stacks with a single command. The CDK resolves the dependency order automatically:

npx cdk --app "npx ts-node bin/app-v2.ts" deploy --all

When prompted, review the AWS Identity and Access Management (IAM) changes and confirm the deployment. The CDK deploys the following stacks:

Stack What it creates
CdcMskCluster Amazon MSK cluster (2x kafka.m5.large brokers) with dual authentication (IAM for Firehose, unauthenticated for Debezium), custom configuration with auto.create.topics.enable=true, security groups with ingress rules for Aurora and MSK Connect workers
CdcMskConnectIam MSK Connect service execution role with permissions for Kafka cluster operations, VPC networking, S3 plugin access, and AWS Secrets Manager; Amazon CloudWatch Logs group for connector logs
CdcS3Tables S3 table bucket, aurora_cdc namespace, two Iceberg tables (orders, products) with column schemas
CdcLambdaTransform Lambda function for CDC event transformation and multi-table routing
CdcFirehoseRole Firehose IAM role with permissions for Amazon MSK, S3 Tables, AWS Glue Data Catalog, AWS Lake Formation, VPC networking, and Lambda invocation
CdcFirehose Firehose delivery stream with MSK as source (private connectivity through AWS PrivateLink), Lambda processing, Apache Iceberg Tables as destination with two table configurations, and S3 backup bucket for failed records

The MSK cluster takes approximately 25 minutes to create. The Debezium connector takes approximately 5 minutes after the cluster is ready. You can monitor the deployment progress in the AWS CloudFormation console.

After the deployment completes, you can verify the resources in the AWS console. The S3 table bucket shows the two Iceberg tables in the aurora_cdc namespace.

Figure 2. S3 table bucket showing the orders and products Iceberg tables in the aurora_cdc namespace.

Figure 2. S3 table bucket showing the orders and products Iceberg tables in the aurora_cdc namespace.

The Firehose delivery stream shows the MSK source, Lambda transformation, and Apache Iceberg Tables destination.

Figure 3. Amazon Data Firehose delivery stream with MSK source, Lambda transformation, and Apache Iceberg Tables destination.

Figure 3. Amazon Data Firehose delivery stream with MSK source, Lambda transformation, and Apache Iceberg Tables destination.

The MSK cluster uses dual authentication (IAM for Firehose, unauthenticated for Debezium through TLS_PLAINTEXT), multi-VPC private connectivity for Firehose PrivateLink access, and auto.create.topics.enable=true so Debezium can create topics on first connect. VPC connectivity and the cluster resource policy are configured as CLI steps in Step 5.

Step 5: Enable MSK VPC connectivity, grant Lake Formation permissions, and apply MSK cluster policy

After the CDK deployment completes, enable multi-VPC private connectivity with IAM on the MSK cluster. Firehose requires this to create an AWS PrivateLink endpoint to the MSK brokers. This setting can’t be configured during cluster creation and must be applied as an update, which triggers a rolling broker restart (approximately 20–30 minutes).

# Get the cluster ARN and current version from the CdcMskCluster stack outputs
MSK_ARN=<msk-cluster-arn>
CLUSTER_VERSION=$(aws kafka describe-cluster-v2 \
    --cluster-arn $MSK_ARN \
    --region <your-region> \
    --query 'ClusterInfo.CurrentVersion' --output text)
# Enable VPC connectivity with IAM
aws kafka update-connectivity \
    --cluster-arn $MSK_ARN \
    --current-version $CLUSTER_VERSION \
    --connectivity-info '{"VpcConnectivity":{"ClientAuthentication":{"Sasl":{"Iam":{"Enabled":true}}}}}' \
    --region <your-region>

Wait for the cluster state to return to ACTIVE before proceeding:

aws kafka describe-cluster-v2 \
    --cluster-arn $MSK_ARN \
    --region <your-region> \
    --query 'ClusterInfo.State'

Next, grant the Firehose IAM role permissions through AWS Lake Formation. S3 Tables uses a sub-catalog format for the CatalogId parameter, which differs from the standard AWS Glue Data Catalog. These permissions require a data lake administrator identity.

Grant database-level and table-level permissions to the Firehose role:

# Grant database-level permissions
aws lakeformation grant-permissions \
    --region <your-region> \
    --principal '{"DataLakePrincipalIdentifier": "<firehose-role-arn>"}' \
    --resource '{"Database": {"CatalogId": "<account-id>:s3tablescatalog/<table-bucket-name>", "Name": "aurora_cdc"}}' \
    --permissions '["ALL"]'
# Grant table-level permissions (wildcard for the tables in the namespace)
aws lakeformation grant-permissions \
    --region <your-region> \
    --principal '{"DataLakePrincipalIdentifier": "<firehose-role-arn>"}' \
    --resource '{"Table": {"CatalogId": "<account-id>:s3tablescatalog/<table-bucket-name>", "DatabaseName": "aurora_cdc", "TableWildcard": {}}}' \
    --permissions '["ALL"]'

Note the CatalogId format: <account-id>:s3tablescatalog/<table-bucket-name>. This is specific to S3 Tables and tells Lake Formation to look up permissions in the S3 Tables catalog rather than the default Glue Data Catalog. For more information, see Integrating Amazon S3 Tables with AWS analytics services.

Next, attach a resource-based policy to the MSK cluster that grants the Firehose service principal permission to create VPC connections:

aws kafka put-cluster-policy \
    --cluster-arn <msk-cluster-arn> \
    --region <your-region> \
    --policy '{
"Version": "2012-10-17",
"Statement": [{
"Effect": "Allow",
"Principal": {"Service": "firehose.amazonaws.com"},
"Action": ["kafka:CreateVpcConnection", "kafka:GetBootstrapBrokers", "kafka:DescribeClusterV2"],
"Resource": "<msk-cluster-arn>"
}]
}'

You can find the <msk-cluster-arn> in the CdcMskCluster stack outputs from Step 4, and the <firehose-role-arn> in the CdcFirehoseRole stack outputs.

Step 6: Create the Debezium connector

With the MSK cluster running and Lake Formation permissions in place, create the Debezium connector using the MSK Connect API. The connector reads changes from Aurora PostgreSQL and publishes them to the MSK topic.

Firehose supports only one MSK topic per delivery stream, so each source table would otherwise need its own Firehose stream and VPC connection. To avoid this, the connector uses the Debezium ByLogicalTableRouter Single Message Transform (SMT) to route changes from multiple tables into a single topic (aurora.cdc.all-tables). The Lambda function then uses the source table name in each message to direct records to the correct Iceberg table. This single-topic pattern uses one Firehose stream for multiple tables, reducing cost and operational complexity.

First, retrieve the MSK bootstrap servers from the cluster:

aws kafka get-bootstrap-brokers \
    --cluster-arn <msk-cluster-arn> \
    --region <your-region>

Note the BootstrapBrokerString value (the PLAINTEXT brokers). Then create the connector:

aws kafkaconnect create-connector --cli-input-json '{
"connectorName": "aurora-postgres-debezium-connector",
"kafkaCluster": {
"apacheKafkaCluster": {
"bootstrapServers": "<bootstrap-servers>",
"vpc": {
"subnets": ["<subnet-1>", "<subnet-2>"],
"securityGroups": ["<msk-security-group-id>"]
}
}
},
"kafkaClusterClientAuthentication": {"authenticationType": "NONE"},
"kafkaClusterEncryptionInTransit": {"encryptionType": "PLAINTEXT"},
"kafkaConnectVersion": "2.7.1",
"plugins": [{"customPlugin": {"customPluginArn": "<custom-plugin-arn>", "revision": 1}}],
"serviceExecutionRoleArn": "<msk-connect-service-role-arn>",
"capacity": {"provisionedCapacity": {"mcuCount": 2, "workerCount": 2}},
"workerConfiguration": {"workerConfigurationArn": "<worker-config-arn>", "revision": 1},
"connectorConfiguration": {
"connector.class": "io.debezium.connector.postgresql.PostgresConnector",
"tasks.max": "1",
"database.hostname": "<aurora-cluster-endpoint>",
"database.port": "5432",
"database.user": "<db-user>",
"database.password": "<db-password>",
"database.dbname": "<database-name>",
"database.server.name": "aurora_cdc",
"plugin.name": "pgoutput",
"slot.name": "debezium_slot",
"publication.name": "dbz_publication",
"table.include.list": "public.orders,public.products",
"topic.prefix": "aurora.cdc",
"schema.history.internal.kafka.topic": "schema-changes.aurora",
"schema.history.internal.kafka.bootstrap.servers": "<bootstrap-servers>",
"decimal.handling.mode": "string",
"time.precision.mode": "adaptive_time_microseconds",
"tombstones.on.delete": "false",
"snapshot.mode": "initial",
"publication.autocreate.mode": "filtered",
"transforms": "Reroute",
"transforms.Reroute.type": "io.debezium.transforms.ByLogicalTableRouter",
"transforms.Reroute.topic.regex": "aurora\\\\\\\\.cdc\\\\\\\\.public\\\\\\\\.(.*)",
"transforms.Reroute.topic.replacement": "aurora.cdc.all-tables"
},
"logDelivery": {
"workerLogDelivery": {
"cloudWatchLogs": {
"enabled": true,
"logGroup": "/aws/msk-connect/aurora-cdc-debezium"
}
}
}
}'

The <msk-security-group-id> and <msk-connect-service-role-arn> can be found in the CdcMskCluster and CdcMskConnectIam stack outputs respectively. The ByLogicalTableRouter Single Message Transform routes CDC events from the monitored tables into a single topic (aurora.cdc.all-tables).

Step 7: Verify the Debezium connector

After creating the connector, verify that it is running and has completed its initial snapshot.

aws kafkaconnect list-connectors --region <your-region> \
    --query 'connectors[?connectorName==`aurora-postgres-debezium-connector`].{Name:connectorName,State:connectorState}' \
    --output table

The connector state should show RUNNING, as shown in the following figure.

Figure 4. Debezium connector running on Amazon MSK Connect.

Figure 4. Debezium connector running on Amazon MSK Connect.

Check the CloudWatch Logs to confirm the snapshot completed:

aws logs tail /aws/msk-connect/aurora-cdc-debezium --follow --region <your-region>

You should see messages indicating the transition to streaming mode:

Finished exporting 0 records for table 'public.orders' (1 of 2 tables)
Finished exporting 0 records for table 'public.products' (2 of 2 tables)
Snapshot completed
Starting streaming

If the tables were empty when the connector started, the export count is 0. If you had existing data, the snapshot captures the existing rows as r (read) operations, which the Lambda function maps to insert operations in the Iceberg tables.

Verify that the Firehose delivery stream is active:

aws firehose describe-delivery-stream \
    --delivery-stream-name msk-to-s3tables-firehose \
    --region <your-region> \
    --query 'DeliveryStreamDescription.DeliveryStreamStatus'

The status should return ACTIVE.

Step 8: Test the pipeline

Insert test data into the Aurora PostgreSQL source tables. Each insert triggers a CDC event that flows through the pipeline: Aurora WAL to Debezium to MSK topic to Firehose to Lambda transform to S3 Tables.

-- Insert orders
INSERT INTO public.orders (customer_id, order_date, total_amount, status)
VALUES
(1, '2026-01-20', 299.99, 'shipped'),
(2, '2026-01-21', 149.50, 'processing'),
(1, '2026-01-22', 89.99, 'delivered');
-- Insert products
INSERT INTO public.products (product_name, category, price, stock_quantity)
VALUES
('Wireless Headphones', 'Electronics', 79.99, 150),
('Running Shoes', 'Sports', 129.99, 75),
('Coffee Maker', 'Kitchen', 49.99, 200);

This creates six records across two tables. Each record generates a Debezium CDC event with operation type c (create), which the Lambda function maps to an insert operation in the corresponding Iceberg table.

Step 9: Verify data delivery

Check the Firehose IncomingRecords metric to confirm records are flowing through the delivery stream:

aws cloudwatch get-metric-statistics \
    --namespace AWS/Firehose \
    --metric-name IncomingRecords \
    --dimensions Name=DeliveryStreamName,Value=msk-to-s3tables-firehose \
    --start-time $(date -u -v-10M +%Y-%m-%dT%H:%M:%S) \
    --end-time $(date -u +%Y-%m-%dT%H:%M:%S) \
    --period 60 --statistics Sum \
    --region <your-region>

You should see a Sum value of 6 or more. If the value is 0, wait another minute and retry. There can be a short delay between MSK topic delivery and Firehose metric reporting.

If records aren’t appearing, check the Firehose error output in the backup S3 bucket and the Lambda function’s CloudWatch Logs for transformation errors.

Step 10: Query data using Amazon Athena

With data delivered to S3 Tables, you can query the Iceberg tables using Amazon Athena. S3 Tables integrates with the AWS Glue Data Catalog as a sub-catalog, so you reference tables using the S3 Tables catalog format.

Tip: If records aren’t appearing in Athena, check the Firehose IncomingRecords CloudWatch metric and the Lambda function’s CloudWatch Logs for transformation errors.

Open the Athena console, select the AwsDataCatalog data source, and run the following queries:

SELECT * FROM "s3tablescatalog/<table-bucket-name>"."aurora_cdc"."products" LIMIT 10;
SELECT * FROM "s3tablescatalog/<table-bucket-name>"."aurora_cdc"."orders" LIMIT 10;

Replace <table-bucket-name> with your S3 table bucket name. You should see the records from the initial snapshot that Debezium captured when the connector started.

The following figures show the initial state of both tables as queried through Athena. At this point, the products table contains seven records and the orders table contains seven records, captured during the Debezium initial snapshot.

Figure 5. Initial state of the products table in Amazon Athena, showing seven records captured from Aurora PostgreSQL through the CDC pipeline.

Figure 5. Initial state of the products table in Amazon Athena, showing seven records captured from Aurora PostgreSQL through the CDC pipeline.

Figure 6. Initial state of the orders table in Amazon Athena, showing seven records captured from Aurora PostgreSQL through the CDC pipeline.

Figure 6. Initial state of the orders table in Amazon Athena, showing seven records captured from Aurora PostgreSQL through the CDC pipeline.

Now test that update and delete operations propagate correctly. Run the following statements in Aurora:

-- Insert new records
INSERT INTO public.products (product_name, category, price, stock_quantity)
VALUES ('Bluetooth Speaker', 'Electronics', 129.99, 90), ('Standing Desk', 'Furniture', 799.99, 20);
INSERT INTO public.orders (customer_id, order_date, total_amount, status)
VALUES (201, '2026-04-03', 149.99, 'NEW'), (202, '2026-04-03', 249.50, 'NEW'), (203, '2026-04-03', 79.90, 'NEW');
-- Update existing records
UPDATE public.products SET stock_quantity = 30, price = 549.99 WHERE product_name = 'Ergonomic Chair';
UPDATE public.orders SET status = 'DELIVERED' WHERE order_id = 201;
-- Delete a record
DELETE FROM public.products WHERE product_name = 'Test Widget';

Wait for the changes to propagate through the pipeline, then query Athena again. The following figures show the results after the insert, update, and delete operations have been applied.

In the products table, the Test Widget record (product_id 100) is no longer present because it was removed by the delete operation. The Ergonomic Chair row now reflects the updated price (549.99) and stock quantity (30). Two new records, Bluetooth Speaker and Standing Desk, appear with a later created_at timestamp, confirming they were inserted after the initial snapshot.

Figure 7. Products table after CDC operations. The Ergonomic Chair, Headphones, and Desk Lamp rows reflect updated values. Bluetooth Speaker and Standing Desk are newly inserted records. The Test Widget record has been removed by the delete operation.

Figure 7. Products table after CDC operations. The Ergonomic Chair, Headphones, and Desk Lamp rows reflect updated values. Bluetooth Speaker and Standing Desk are newly inserted records. The Test Widget record has been removed by the delete operation.

In the orders table, order 100 now shows a status of SHIPPED and order 201 shows DELIVERED, reflecting the update operations. Three new orders (301, 302, 303) appear with status NEW and a later timestamp, confirming they were inserted after the initial load.

Figure 8. Orders table after CDC operations. Orders 100 and 201 reflect updated status values. Orders 301, 302, and 303 are newly inserted records.

Figure 8. Orders table after CDC operations. Orders 100 and 201 reflect updated status values. Orders 301, 302, and 303 are newly inserted records.

This confirms that the pipeline correctly handles the three CDC operation types: inserts, updates, and deletes are captured from the Aurora WAL by Debezium, routed through the single MSK topic, transformed by the Lambda function, and applied as row-level Iceberg operations by Firehose.

S3 Tables handles compaction and snapshot management for Iceberg tables automatically, including compaction of small data files and expiration of old snapshots. You don’t need to run manual maintenance operations.

You can also use Iceberg’s time travel capability to query the table as it existed before the updates:

SELECT * FROM "s3tablescatalog/<table-bucket-name>"."aurora_cdc"."orders"
FOR TIMESTAMP AS OF current_timestamp - interval '5' minute;

This returns the original data before the update, demonstrating the time travel capability that Apache Iceberg provides through S3 Tables.

Cleaning up

To avoid ongoing charges, delete the resources in reverse dependency order.

Delete the CDK stacks:

cd cdk
npx cdk --app "npx ts-node bin/app-v2.ts" destroy --all

Delete the Debezium custom plugin and worker configuration that were created through the AWS CLI in Step 2:

aws kafkaconnect delete-custom-plugin --custom-plugin-arn <plugin-arn>
aws kafkaconnect delete-worker-configuration --worker-configuration-arn <worker-config-arn>

Clean up the Aurora PostgreSQL replication resources:

SELECT pg_drop_replication_slot('debezium_slot');
DROP PUBLICATION dbz_publication;

Important: The replication slot (debezium_slot) was created automatically by Debezium. If you plan to redeploy the pipeline later, you don’t need to drop the slot and publication. However, the replication slot continues to retain WAL segments while the connector isn’t running, which can increase storage usage on the Aurora cluster. The MSK cluster is the largest cost component of this solution and can’t be paused. It can only be deleted and recreated.

Conclusion

In this post, we showed you how to build a near real-time CDC pipeline from Aurora PostgreSQL to Apache Iceberg tables in Amazon S3 Tables. The key architectural decisions include:

  • Single-topic routing with multi-table delivery. The Debezium ByLogicalTableRouter SMT routes CDC events from multiple tables through one MSK topic, and the Lambda otfMetadata routing directs each record to the correct Iceberg table. This reduces VPC connection costs by using a single Firehose stream for inserts, updates, and deletes across multiple destination tables.
  • Fully managed CDC pipeline. MSK Connect runs Debezium, Firehose handles delivery with automatic retries, and S3 Tables manages Iceberg compaction and snapshots. The Lambda transform preserves CDC semantics by mapping Debezium operations to Iceberg row-level operations.
  • Governed lakehouse access. Lake Formation controls fine-grained access to the Iceberg tables, and data from multiple isolated Aurora clusters can be unified in a single S3 Tables namespace for cross-domain analytics.
  • Infrastructure as code. Six AWS CDK stacks deploy the core pipeline, with Lake Formation permissions, MSK cluster policy, and Debezium connector configured through documented CLI steps.

To get started, clone the sample repository and follow the walkthrough steps. For more information about the services used in this solution, see the Amazon MSK Developer Guide, Amazon Data Firehose Developer Guide, and Amazon S3 Tables User Guide.

We encourage you to try this solution and adapt it to your own CDC workloads. If you have questions or feedback, leave a comment on this post.


About the author
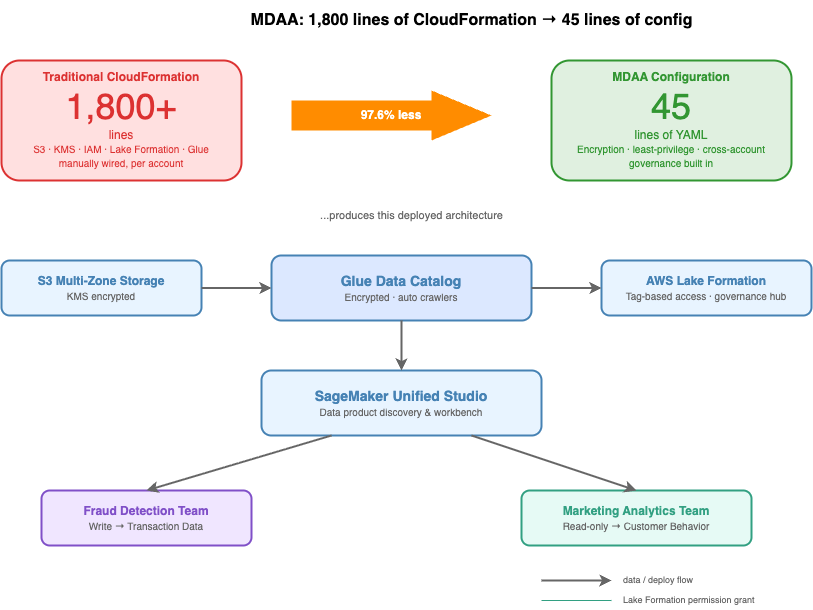
Chintan Agrawal

Chintan Agrawal

Chintan is a Solutions Architect with over 7 years of experience, with a specialization in Analytics and Healthcare domain. He possesses a strong enthusiasm for assisting clients in discovering valuable insights from their data. Through his expertise, he constructs innovative solutions that empower businesses to arrive at informed, data-driven choices.
Integrating Event Source Mappings with AWS Lambda tenant isolation mode

Post Syndicated from Anton Aleksandrov original https://aws.amazon.com/blogs/compute/integrating-event-source-mappings-with-aws-lambda-tenant-isolation-mode/

Building event-driven multi-tenant SaaS applications typically requires compute isolation between tenants to prevent data leakage, maintain security boundaries, and ensure compliance. Traditionally, you had to choose between two approaches: sharing execution environments across tenants (risking cross-tenant contamination of in-memory state) or managing separate Lambda functions per tenant (which introduces operational overhead, increasing costs, and complicating deployments). Both approaches required you to make trade-offs between security, operational complexity, and cost efficiency.

AWS Lambda tenant isolation mode with Event Source Mappings addresses this trade-off. This approach reduces operational complexity, improves your security posture, and removes the need to manage separate functions per tenant, all while maintaining strict compute-level isolation boundaries. You can now build event-driven architectures using services like Amazon SQS and Amazon EventBridge where each tenant’s workloads run in dedicated execution environments, but you manage only a single Lambda function.

In this post, you’ll learn how to propagate tenant identity from event payloads, implement IAM permissions for tenant-isolated invocations, apply validation strategies to verify tenant context, and use a lightweight routing mechanism that invokes tenant-isolated backends. Complete sample code demonstrating this pattern is available in the AWS samples repository.

Understanding Lambda tenant isolation mode

AWS Lambda tenant isolation mode extends Lambda’s execution model by introducing tenant-aware routing of invocations. Instead of reusing execution environments across all invocations of a function, Lambda associates each execution environment with a specific tenant identifier. When a new request is received, Lambda routes it to an existing environment for that specific tenant or creates a new one if none exists.

Tenant Isolation ArchitectureFigure 1. Using Lambda tenant isolation mode for compute isolation

This simplifies how you build multi-tenant SaaS systems, while maintaining isolation boundaries at the compute level. Execution environments are never shared across tenants but still reused within the same tenant for maximum efficiency. That means you can safely cache tenant-specific configurations, such as feature flags or database connection strings, without adding isolation logic manually in your code.

To use the tenant isolation mode, every invocation must include a tenant ID parameter. For synchronous, direct invocations, such as originating from Amazon API Gateway or AWS SDKs, you pass it using the X-Amz-Tenant-Id header, as described in the launch blog and service documentation. Lambda service uses this header to route the invocation to tenant-specific execution environments. Inside your function handler, the tenant ID is available using the context.tenantId property, so you can implement tenant-aware logic.

port const handler = async (event, context) => {
    const tenantId = context.tenantId;

    // Tenant-specific business logic here
    console.log(`Processing request for tenant: ${tenantId}`);
};

Figure 2. Accessing tenant ID from function handler.

When using API Gateway, you can extract the tenant ID value from incoming request metadata, such as HTTP headers, path parameters, query parameters, or JWT claims, and map it directly to the downstream X-Amz-Tenant-Id in the API Gateway integration request configuration. See the launch blog for detailed guidance.

This model works well for direct, synchronous invocations. However, many serverless applications rely on event-driven patterns, where Lambda is invoked through Event Source Mappings.

Using tenant isolation mode with event sources

Many serverless applications use event-driven architectures built on services like Amazon SQS, Amazon EventBridge, Amazon Kinesis, or Amazon DynamoDB Streams. In these cases, Lambda is invoked by an Event Source Mapping (ESM), which polls the event source and invokes your function when new events arrive.

With these services, you’ll commonly find the tenant identity embedded in the event payload or metadata – for example, in an SQS message body or EventBridge event detail. Each event source has its own payload schema. Below are example payloads when using SQS and EventBridge, where you can see the tenantId parameter present in the payload.

SQS message body:

{
    "tenantId": "TenantA",
    "orderId": "ord-12345",
    "eventType": "ORDER_PLACED",
    "payload": { ... }
}

EventBridge event detail:

{
    "source": "com.myapp.orders",
    "detail-type": "OrderPlaced",
    "detail": {
        "tenantId": "TenantA",
        "orderId": "ord-12345"
    }
}

However, event sources don’t provide a built-in mechanism to map message properties to HTTP headers. As a result, if you try to invoke a function with tenant isolation mode enabled directly from an event source mapping, it fails because the tenant ID isn’t propagated as the X-Amz-Tenant-Id header. The following section describes how to address this and integrate ESMs with tenant-isolated Lambda functions.

Propagating tenant identity with Event Source Mappings

To propagate tenant identity from ESM messages, you can introduce a routing component – a lightweight Lambda function that sits between the event source and your tenant-isolated backend function. Your routing function receives events from the ESM, extracts the tenant ID from each message, and invokes your backend function using the Lambda Invoke API, passing the required X-Amz-Tenant-Id header. See the following diagram for an example architecture using SQS ESM.

Lambda with tenant isolated SQS

Figure 3. Propagating tenant ID from SQS messages to Lambda with tenant isolation mode enabled

You don’t need to enable tenant isolation mode on the routing function itself – it acts as a stateless dispatcher. Your multi-tenant backend function, which contains your core business logic, runs with tenant isolation mode enabled and receives properly scoped, tenant-aware invocations. This pattern keeps tenant isolation at the backend layer while preserving a shared event ingestion model.

The following example illustrates a routing function that processes incoming SQS messages, extracts the tenant ID from each message body, and invokes your backend function with the appropriate tenant context. This example assumes MessageGroupId is used to carry the tenant identifier, which ensures messages from the same tenant are processed in order when you’re using FIFO queues.

export const handler = async (event) => {
    for (const record of event.Records) {
        const body = record.body;
        const messageGroupId = record.attributes?.MessageGroupId;

        const command = new InvokeCommand({
            FunctionName: BACKEND_FUNCTION_NAME,
            InvocationType: 'Event',
            TenantId: messageGroupId,
            Payload: Buffer.from(body)
        });

        await lambdaClient.send(command);
    }
}

Figure 4. Routing SQS messages to a Lambda function with tenant isolation mode enabled

The following example illustrates how you can achieve the same routing functionality when processing EventBridge events.

export const handler = async (event) => {
    const tenantId = event.detail?.tenantId;

    if (!tenantId) {
        throw new Error(`Missing tenantId in EventBridge event: ${JSON.stringify(event)}`);
    }

    const command = new InvokeCommand({
        FunctionName: BACKEND_FUNCTION_NAME,
        InvocationType: 'Event',
        TenantId: tenantId,
        Payload: JSON.stringify(event.detail),
    });

    await lambdaClient.send(command);
};

Figure 5. Routing EventBridge events to a Lambda function with tenant isolation mode enabled

IAM permissions

Your routing function’s execution role needs permission to:

  1. Poll the event source: You can apply this policy either to your function execution role or as a resource policy on the event source itself.
  2. Invoke the downstream backend function: Additionally, your router function requires the lambda:InvokeFunction permission scoped to your backend function ARN.

Below is an example execution role policy to allow the router function to poll from an SQS queue

{
    "Version": "2012-10-17",
    "Statement": [{
        "Effect": "Allow",
        "Action": [
            "sqs:ReceiveMessage",
            "sqs:DeleteMessage",
            "sqs:GetQueueAttributes"
        ],
        "Resource": "arn:aws:sqs:us-east-1:123456789012:my-queue"
    }]
}

Below is an example execution role policy to allow the router function to invoke the backend function

{
    "Version": "2012-10-17",
    "Statement": [{
        "Effect": "Allow",
        "Action": "lambda:InvokeFunction",
        "Resource": "arn:aws:lambda:us-east-1:123456789012:function:my-backend-function"
    }]
}

Figure 6. IAM permissions used for implementing the tenant ID router function mechanism.

Best practices and considerations

When implementing the pattern described in this post, keep these important considerations in mind regarding validation, scaling, and overall system design.

Validate tenant identity before invocation. Tenant identity comes from event payloads, you shouldn’t automatically assume it’s trustworthy. Here’s how to protect your system:

  • Validate incoming payloads and reject messages with missing, malformed, or unauthorized tenant IDs at the routing layer before invoking your backend function
  • Maintain an authoritative tenant registry and validate incoming tenant IDs against it
  • Use dead-letter queues (DLQs) on your SQS queues to capture messages that fail validation for investigation and replay
  • When using EventBridge Pipes, use the enrichment step to validate or normalize tenant IDs before they reach your routing function
  • Enable partial batch response for applicable ESMs, such as SQS, so your routing function can report individual message failures without failing the entire batch

Plan for scaling considerations. Tenant isolation mode creates separate execution environments per tenant. This can increase the number of cold starts compared to shared environments. Each tenant consumes concurrency independently, so monitor your usage and request quota increases as your tenant base grows.

Optimize the routing function. Your routing function introduces an additional invocation segment. Use asynchronous invocation (InvocationType: ‘Event’) to reduce idle waiting time and size your function accordingly.

Understand permission boundaries. Tenants share your backend function’s execution role. If you need fine-grained per-tenant permissions, consider propagating tenant-scoped credentials (for example, using AWS STS AssumeRole) from the upstream segment.

Sample code

A complete, deployable sample project demonstrating this pattern – including SQS routing functions, a tenant-isolated backend function, and AWS SAM infrastructure – is available in this GitHub repository. Follow the instructions in README.md to provision the sample project in your account

Conclusion

Lambda tenant isolation mode introduces cross-tenant compute isolation for your multi-tenant SaaS applications by routing each invocation to a tenant-specific execution environment. When you combine this with event-driven architectures built on services like SQS, EventBridge, and Kinesis, the routing function pattern described in this post allows you to propagate tenant identity from event payloads and invoke your tenant-isolated backend with the correct context.

This approach extends tenant isolation mode to your asynchronous workloads without changing your core business logic. You retain per-tenant execution environment isolation while continuing to use Lambda’s native event source integrations, scaling model, and operational tooling. Together, these patterns provide you with a practical foundation for building secure, scalable, event-driven multi-tenant SaaS applications on AWS.

Next steps: Consider extending this pattern to other event sources like Kinesis Data Streams or DynamoDB Streams. You can also explore combining this approach with AWS Step Functions for orchestrating complex multi-tenant workflows while maintaining tenant isolation boundaries.

Follow below links to learn more: