Tag Archives: Technical How-to

Enhance email security using VPC endpoints with Amazon SES

Post Syndicated from Mamadou Ba original https://aws.amazon.com/blogs/messaging-and-targeting/enhance-email-security-using-vpc-endpoints-with-amazon-ses/

Email’s universal adoption and accessibility make Amazon Simple Email Service (Amazon SES) an ideal platform for delivering critical business communications, such as customer notifications or password resets. However, the ubiquity of email also invites bad actors who seek to actively exploit email’s ubiquity to launch sophisticated attacks. Business email transmissions traverse a complex network with potential vulnerabilities, making email systems prime targets for these malicious actors. Common threats include message interception, email spoofing, unauthorized access to sending services, and service disruption attacks.

Amazon SES handles millions of sensitive communications daily. For example, healthcare providers transmit patient data, financial institutions send transaction alerts, and businesses exchange confidential information. Securing this critical infrastructure requires deep expertise in email systems, threat detection, and advanced security protocols to provide message integrity and confidentiality.

In this post, we discuss and guide you in enhancing your email security by using VPC endpoints with Amazon SES.

Common security challenges customers face sending email with Amazon SES

Consider the challenges faced by a large healthcare provider seeking to send automated appointment reminders and confidential lab results. Although Amazon SES meets their email delivery needs, the IT team must implement strict security measures to satisfy industry, government, and internal requirements. These likely include secure SMTP connections, identity-based access controls, and network isolation to safeguard sensitive patient information.

These common security requirements seek to address two critical concerns. First, they aim to prevent unauthorized access to the organization’s Amazon SES accounts, thereby safeguarding sensitive communications from potential breaches. Second, these measures mitigate the risks of bad actors co-opting their Amazon SES accounts to launch sophisticated email spoofing and phishing attacks.

Either breach could compromise trusted domains, undermining the security of the healthcare provider’s email communications and damaging their reputation.

For organizations with specific network security requirements or compliance mandates, Amazon SES offers VPC endpoint integration to provide additional network-level controls. This approach is particularly valuable for customers who prefer to avoid API calls traversing the public internet or need to ensure email processing workflows remain within private network boundaries.

VPC endpoints create a direct connection between your applications and Amazon SES, offering the following capabilities:

  • Enhanced network isolation: Keeps email traffic within your private network infrastructure
  • Compliance alignment: Supports regulatory frameworks like HIPAA and GDPR that may require additional network controls
  • Network-based access controls: Restricts SES access to authorized IP ranges and subnets
  • Simplified hybrid connectivity: Leverages existing VPN or Direct Connect infrastructure for seamless integration
  • Defense-in-depth architecture: Adds an additional layer of network security to your email infrastructure

Amazon SES VPC endpoints are enabled by AWS PrivateLink for SMTP message traffic. With these VPC endpoints, you can route SMTP email traffic privately within the AWS network between your sending applications, optionally with encryption, and Amazon SES. When using a VPC endpoint, traffic to Amazon SES doesn’t transmit over the internet and never leaves the Amazon network to securely connect your VPC to Amazon SES without availability risks or bandwidth constraints on your network traffic.

At the time of writing, Amazon SES VPC endpoints don’t support API-based email sending (such as SendEmail, SendRawEmail, or SDKs). Amazon SES API traffic should be encrypted and routed using a VPC through a NAT gateway or over the public internet.

Solution overview

Our solution can help you secure your SMTP message traffic by using the following components:

The following diagram illustrates the solution architecture. The architecture assumes you already have connectivity from your on-premises network to your VPC. For instructions to connect your on-premises network to AWS, refer to Hybrid network connections.
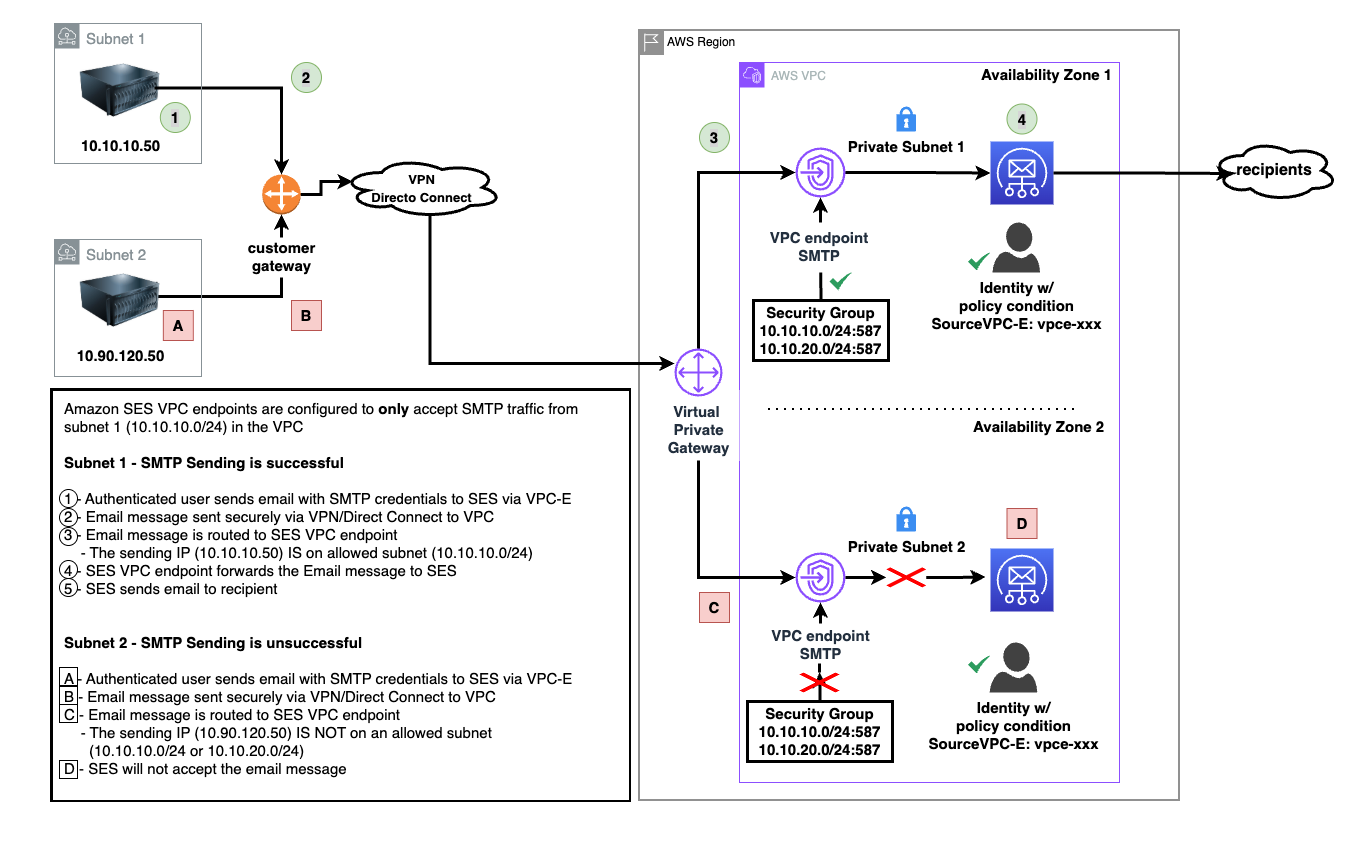
For testing purposes, we use connectivity within AWS. The same concept applies if you’re connecting from an on-premises network that is connected to your VPC either through a Virtual Private Network (VPN) or Direct Connect (DX).

The solution workflow consists of the following steps:

  1. Your SMTP sending applications and services are located on premises or in your data center using two subnets:
    1. Subnet A (IP range: 10.10.10.50)
    2. Subnet B (IP range: 10.90.120.50)
  2. Secure connections are transmitted using AWS Direct Connect or VPN connection to a VPC in the same AWS Region as your Amazon SES account.
  3. The SMTP message traffic, optionally encrypted, is sent to the Amazon SES VPC endpoints configured to restrict network connections from the VPC to only specific subnets:
    1. Traffic on approved subnet A (10.10.10.50) is sent to Amazon SES.
    2. Traffic on denied subnet B (10.90.120.50) is dropped (not sent to Amazon SES).
  4. SMTP traffic from only the allowed subnet A is further restricted to an IAM policy with valid SMTP credentials.
  5. Messages that conform to the traffic and authentication policies are passed to Amazon SES for final delivery to recipients.

Prerequisites

To implement this solution, you must have the following prerequisites:

  • Amazon SES, configured with at least one verified identity, in the same Region as the VPC.
  • An existing VPC in the same Region as Amazon SES. This can be the default VPC. For more information, see Plan your VPC.
  • An SMTP sending application (optionally supporting TLS encryption) located in one of the following options:
    • On premises or in a data center that is connected to the VPC through a private network connection (such as Direct Connect or VPN). For more details about private network connections to AWS, refer to Network-to-Amazon VPC connectivity options.
    • In the VPC running on a compute resource such as Amazon Elastic Compute Cloud (Amazon EC2) or AWS Lambda. For this post, we use an EC2 instance in the VPC and connect to Amazon SES through the VPC endpoint on port 587 with TLS enabled. Note that AWS blocks outbound SMTP traffic on port 25 across most AWS services. Use an alternative TCP port, such as 465, 587, 2465, or 2587. Request port 25 exemption by submitting a request to AWS Support from your AWS account using the “Request to remove email sending limitations” form. This can take upwards of 7 business days to be reviewed; approval is not guaranteed. Amazon SES uses an opportunistic TLS policy by default for encrypting messages when the receiving host supports it. You should use encryption whenever it is available.
  • For testing, you can use one of the following options:
  • DNS resolution for resources in the VPC with the Amazon SES VPC endpoints in the source network. To learn more, see Resolving DNS queries between VPCs and your network.

Create security group

The first step is to create a security group with inbound rules that only allow a specific IP range on the appropriate port (host-permitting, 25, 465, 587, 2465, or 2587). In our example, we only allow subnet A (IP range: 10.10.10.50) on port 587. Complete the following steps to create the security group:

  1. In the navigation pane of the Amazon EC2 console, under Network & Security, choose Security groups.
  2. Choose Create security group.
  3. For Security group name, enter a unique name that identifies the security group (we use ses-vpce-sec-group).
  4. For Description, enter the purpose of the security group.
  5. For VPC, choose the VPC in which you will host the application that will use Amazon SES.
  6. Under Inbound rules, choose Add rule.
  7. For Type, choose Custom TCP.
  8. For Port range, enter the port number that you want to use to send email. You can choose from 465, 587, 2465, or 2587. For this post, we use 587.
  9. For Source type, choose Custom.
  10. Enter the private IP CIDR range for subnet A (IP range: 10.10.10.50), which contains the resources that will use the VPC endpoint to communicate with Amazon SES.
  11. Choose Create security group.

Create VPC endpoint to connect the VPC to Amazon SES

Complete the following steps to create your VPC endpoint:

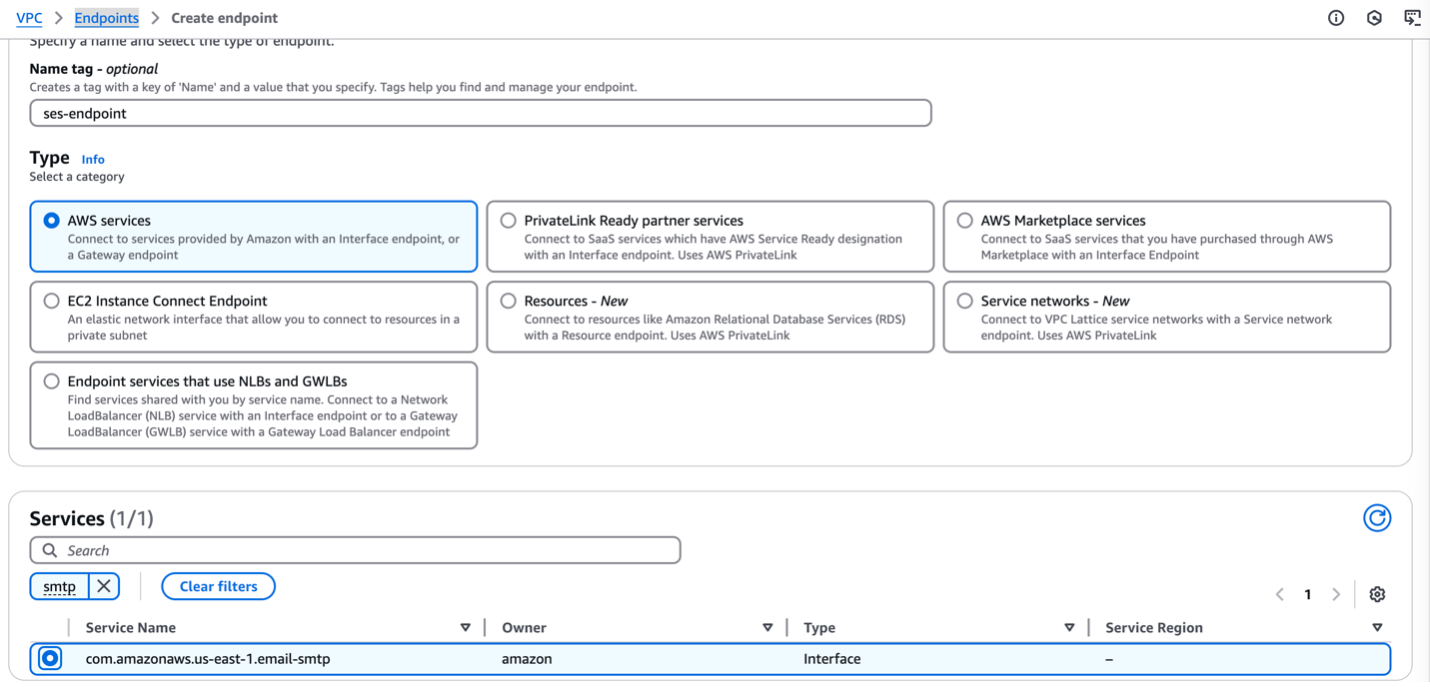
  1. On the Amazon VPC console, in the navigation pane, under PrivateLink and Lattice, choose Endpoints.
  2. Choose Create endpoint.
  3. Optionally, under Endpoint settings, create a tag in the Name tag field.
  4. For Service category, select AWS services.
  5. For Services, filter for and select smtp.
  6. For VPC, choose a VPC (for more details, see Prerequisites).
  7. For Subnets, select Availability Zones and Subnet IDs.
    Amazon SES doesn’t support VPC endpoints in the following Availability Zones: use1-az2, use1-az3, use1-az5, usw1-az2, usw2-az4, apne2-az4, cac1-az3, and cac1-az4.
  1. For Security groups, choose the security group you created earlier.
  2. Optionally, for Tags, create one or more tags.
  3. Choose Create endpoint.
    Wait approximately 5 minutes while Amazon VPC creates the endpoint. When the endpoint is ready to use, the value in the Status column changes to Available.
  4. Copy the VPC endpoint ID to your clipboard to use in the next step.
Optionally, you can test the connection to make sure the VPC endpoint is configured properly by using command line tools to send a test email using the Amazon SES SMTP interface from an EC2 instance in the same VPC where you just created the email-smtp VPC endpoint. For more information, see Using the Amazon SES SMTP interface to send email.

Create SMTP credentials in Amazon SES that will be used by sender applications to authenticate

Complete the following steps to create SMTP credentials:

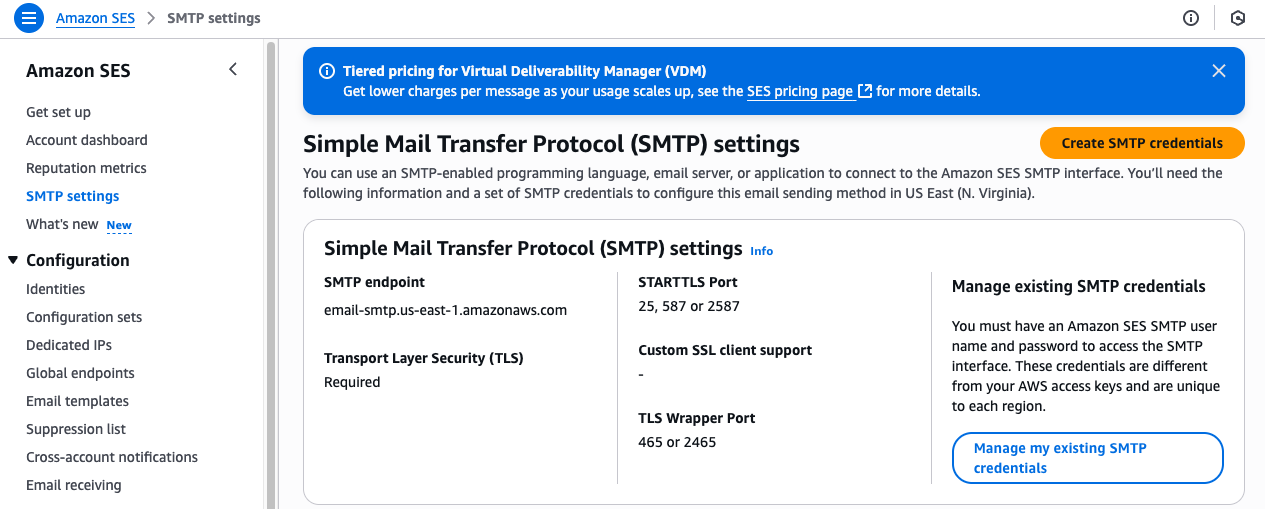
  1. On the Amazon SES console, choose SMTP Settings in the navigation pane.
  2. Choose Create SMTP credentials.
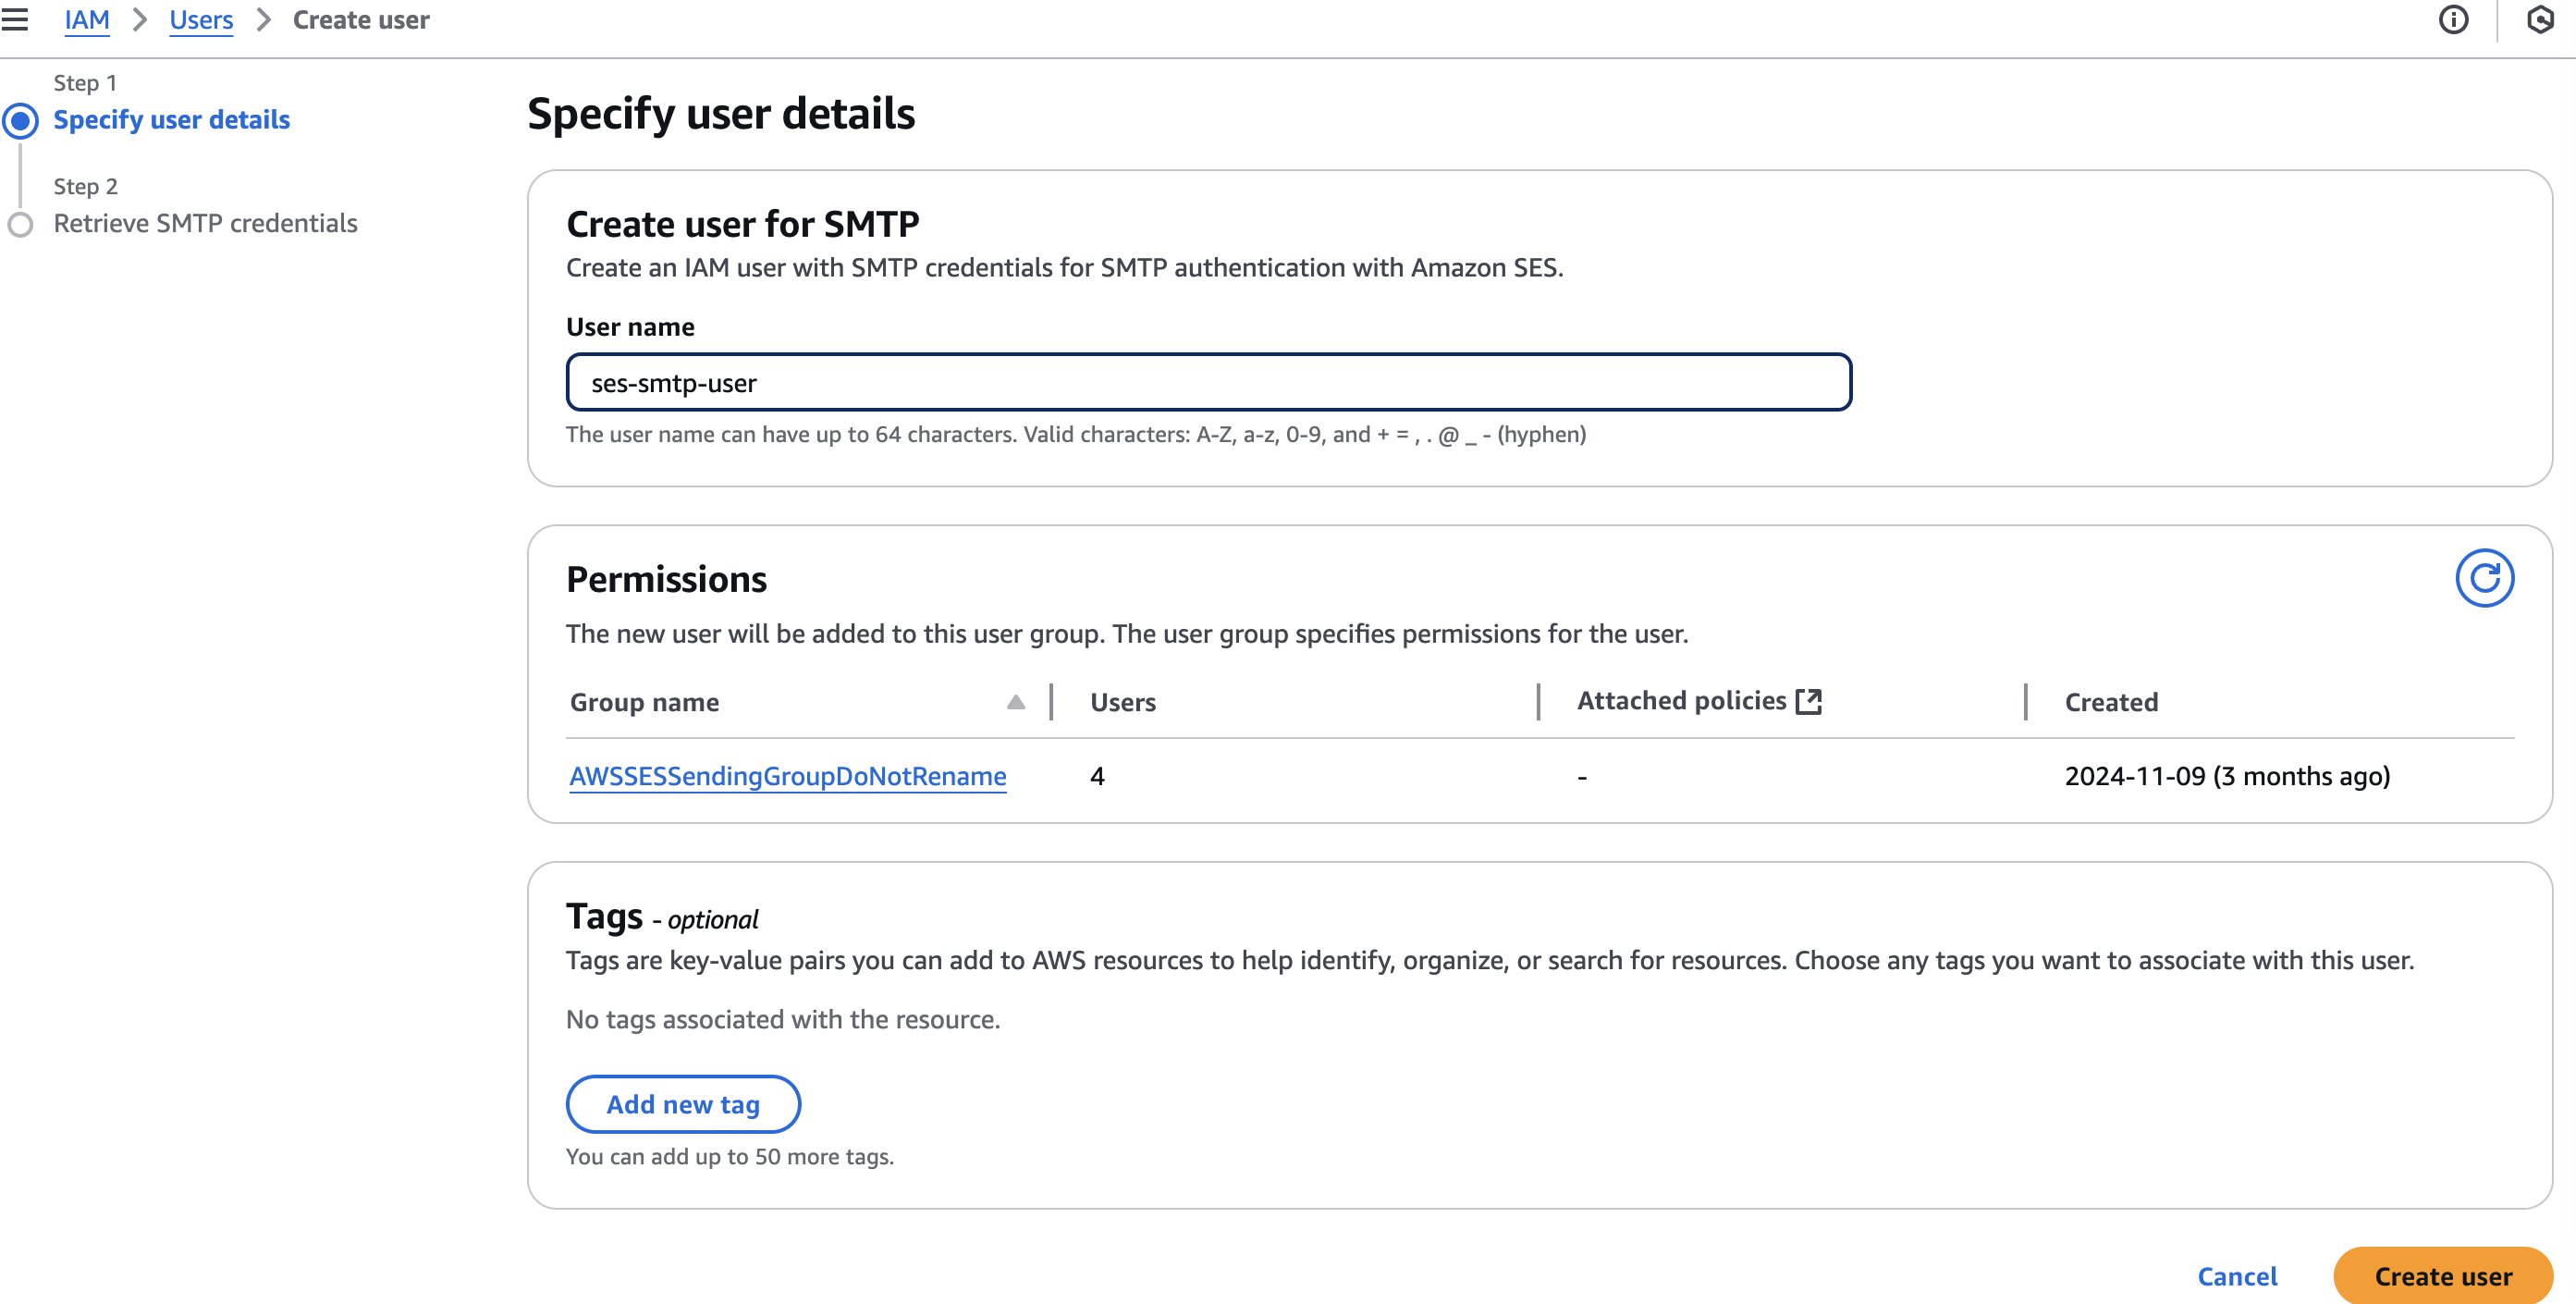
  3. Enter your preferred user name and choose Create user.
  4. Download the user’s SMTP credentials or copy the credentials to AWS Secrets Manager. (we will use these SMTP credentials in the next step).
  5. Return to the SES console.

Limit traffic to the Amazon SES VPC endpoint using IAM

In this step, we limit traffic to the Amazon SES VPC endpoint using an IAM policy. The IAM policy has a condition that restricts access to aws:SourceVpce. Complete the following steps:

  1. On the Amazon SES console, choose SMTP Settings in the navigation pane.
  2. Choose Manage my existing SMTP credentials.
  3. Choose the user you created earlier, then choose Permissions.
  4. Choose the policy name AmazonSesSendingAccess to go to the IAM policy editor.
  5. Replace the policy content in JSON view with the following policy, which adds the conditions for traffic to come from the Amazon SES VPC endpoint:
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "SESSendPermissions",
      "Effect": "Allow",
      "Action": [
        "ses:SendEmail",
        "ses:SendCustomVerificationEmail",
        "ses:SendRawEmail",
        "ses:SendBulkEmail"
      ],
      "Resource": "*",
      "Condition": {
        "StringEquals": {
          "aws:SourceVpce": ""
        }
      }
    }
  ]
}
  1. Choose Next.
  2. Choose Save changes.

As a best practice, rotate your SMTP credentials on a periodic basis and whenever there is concern over the confidentiality of the credentials. For more information, see Automate the Creation & Rotation of Amazon Simple Email Service SMTP Credentials.

Test permissions and connectivity

To test permissions and connectivity by sending a test email, complete the following steps to create an EC2 instance in your VPC:

  1. On the Amazon EC2 console, create a new EC2 instance.
  2. Make sure to specify your VPC and subnet. The subnet must be the same as the one selected in previous steps.
  3. Use the SMTP script in the Amazon SES documentation for testing.

This screenshot shows the test result using the SMTP VPC Endpoint URL.
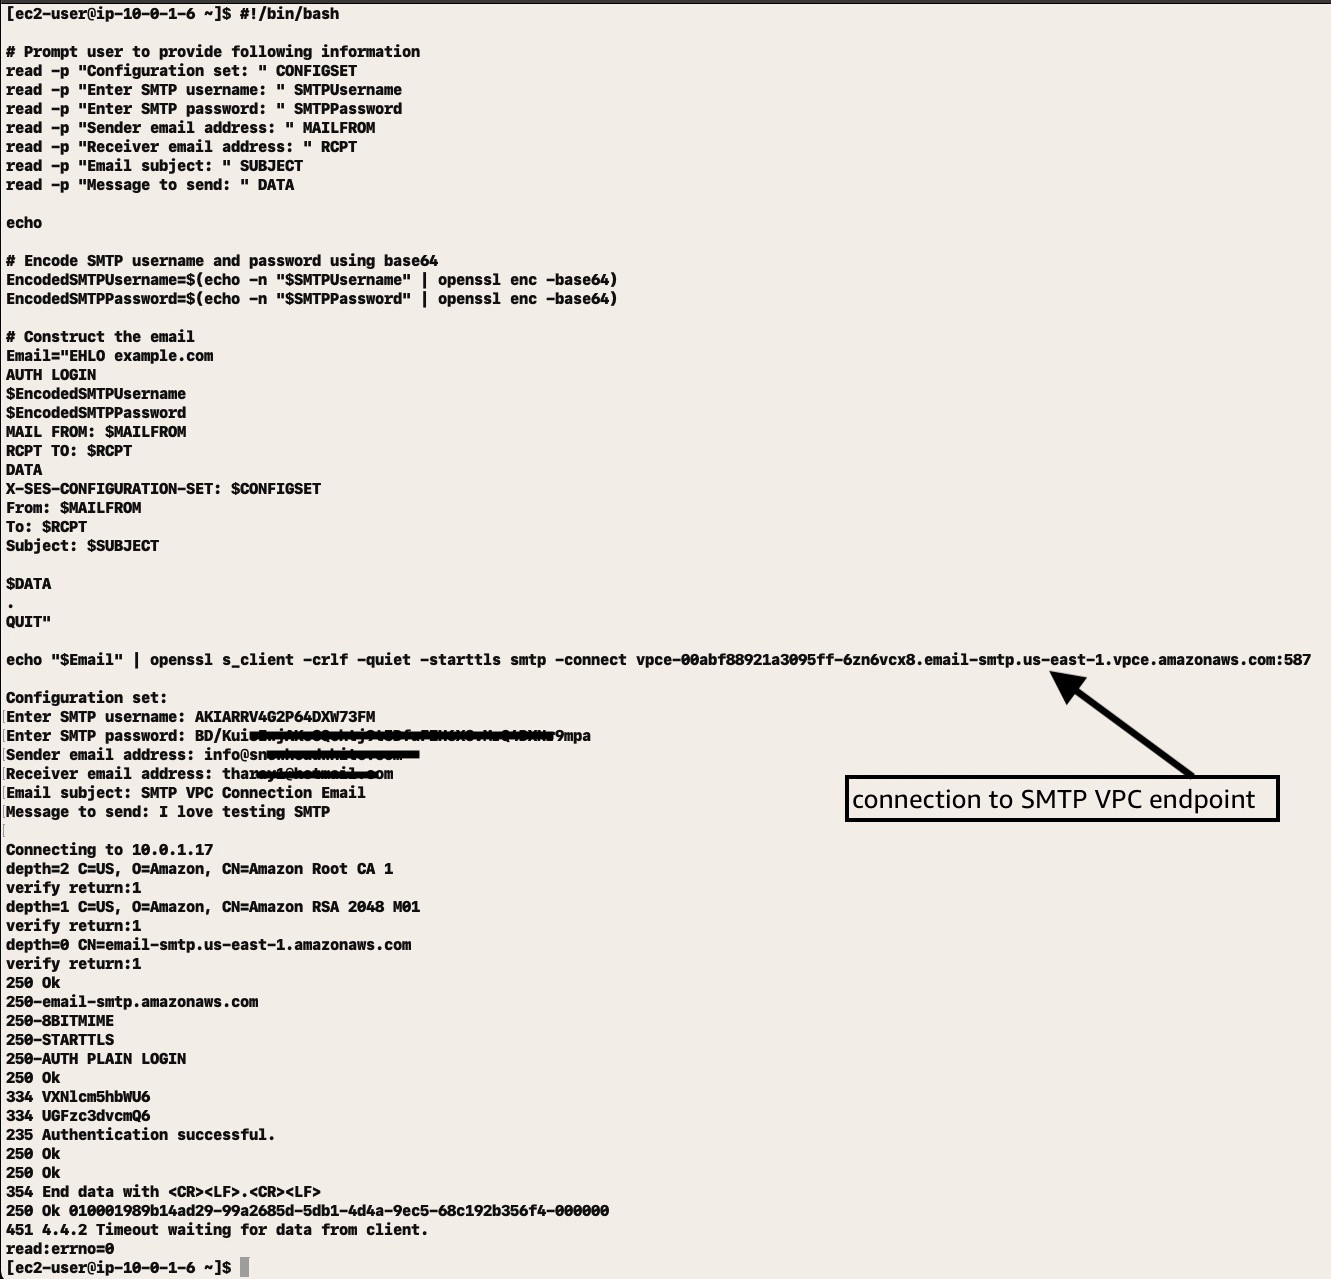
This configuration allows Amazon SES to only accept SMTP message traffic from applications from allowed on-premises subnets with connectivity to AWS and in the VPC that originates from the permitted SMTP IAM identity policy. This design follows the AWS least privilege access approach to security. To learn more, refer to Strategies for achieving least privilege at scale.

Clean up

After testing, if you don’t want to keep these configurations you should delete the EC2 instance, the VPC endpoint, the SMTP credential, and the IAM user.

Conclusion

In this post, we demonstrated how to implement a secure Amazon SES environment by combining multiple AWS security controls. By using Amazon SES VPC endpoints, security groups, and IAM policies, you can create a robust security architecture that restricts email sending capabilities to authorized networks only.

This multi-layered approach addresses critical security challenges by avoiding public internet exposure for SMTP traffic, enabling comprehensive traffic monitoring through VPC flow logs, and establishing defined network boundaries that satisfy strict compliance requirements.

The solution provides significant security benefits while maintaining the scalability and reliability that Amazon SES customers expect. Organizations can effectively protect sensitive email communications, prevent unauthorized access, and maintain compliance with industry regulations like HIPAA and GDPR. This becomes increasingly important as email-based threats continue to evolve and regulatory requirements become more stringent.

Start implementing these security controls today:

  • Deploy this solution in your development environment first, testing each component thoroughly
  • Review the security best practices for Amazon SES and VPC endpoints
  • Validate your implementation against your organization’s security requirements
  • Create a detailed migration plan for your production environment
  • Monitor and audit your email infrastructure regularly using VPC Flow Logs and Amazon CloudWatch

For additional guidance, consult the Amazon SES documentation, explore the AWS Security Blog for related articles, or engage with AWS Support. Remember to periodically review and update your security configurations as new features and best practices emerge.
About the authors

Automate email notifications for governance teams working with Amazon SageMaker Catalog

Post Syndicated from Himanshu Sahni original https://aws.amazon.com/blogs/big-data/automate-email-notifications-for-governance-teams-working-with-amazon-sagemaker-catalog/

Amazon SageMaker Catalog simplifies the discovery, governance, and collaboration for data and AI across Data Lakehouse, AI models, and applications. With Amazon SageMaker Catalog, you can securely discover and access approved data and models using semantic search with generative AI–created metadata or could just ask Amazon Q Developer with natural language to find their data.

Large enterprise customers have multiple lines of businesses who produce and consume data using a central SageMaker Data Catalog. Many customers have a central data governance team that is responsible for creating, publishing, and maintaining data governance standards and best practices across the firm. As the customer’s data platform scales, it becomes challenging for the central governance team to maintain the standards across all data producers and consumers. Because of this, many governance teams need to monitor user activity in Amazon SageMaker Catalog to ensure data assets are published according to established organizational governance standards and best practices. In this scenario, there is a need for automation where the central governance teams can be notified when critical events happen in Amazon SageMaker Catalog.

In this post, we show you how to create custom notifications for events occurring in SageMaker Catalog using Amazon EventBridge, AWS Lambda, and Amazon Simple Notification Service (Amazon SNS). You can expand this solution to automatically integrate SageMaker Catalog with in-house enterprise workflow tools like ServiceNow and Helix.

Solution overview

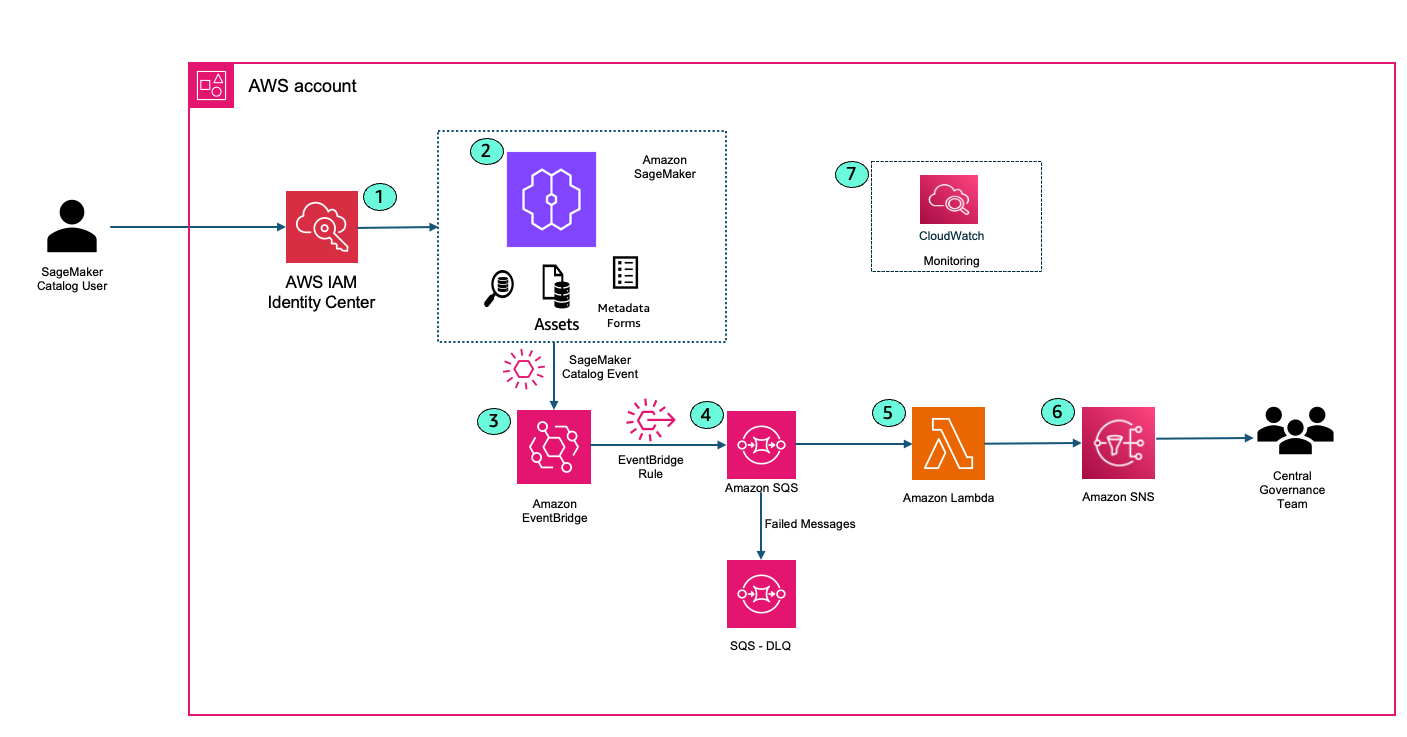
The following solution architecture shows how SageMaker Catalog integrates with other AWS services like AWS IAM Identity Center, Amazon EventBridge, Amazon SQS, AWS Lambda, and Amazon SNS to generate automated notifications to capture critical events in the enterprise catalog.

  1. A SageMaker Catalog user logs into Amazon SageMaker Unified Studio using IAM Identity center. This could be a data scientist, machine learning engineer, or analyst looking for published data sets in the firm. AWS IAM Identity center ensures that only authorized personnel can access the cataloged assets and ML resources.
  2. User performs an activity within SageMaker Catalog. Example user creates a new project or user searches for a data asset and creates a subscription request to access the asset.
  3. User events from SageMaker Catalog are captured in Amazon EventBridge. Amazon EventBridge is a fully managed, serverless event bus service designed to help you build scalable, event-driven applications across AWS, SaaS, and custom applications. Amazon EventBridge provides the ability to filter events and allow users to take action on specific events.The following example event pattern in EventBridge filters DataZone create project events.
    {
      "source": [
        "aws.datazone"
      ],
      "detail": {
        "eventSource": [
          "datazone.amazonaws.com"
        ],
        "eventName": [
          "CreateProject"
        ]
      }
    }

  4. Amazon EventBridge sends the filtered events to Amazon SQS. Routing events to an SQS queue improves reliability and durability. Amazon SQS acts as a buffer between Amazon EventBridge and AWS Lambda, decoupling event producers from consumers. This allows your Lambda functions to process messages at their own pace, preventing overload during traffic spikes or when downstream resources are temporarily slow or unavailable. Amazon SQS provides durable, persistent storage for events. If Lambda service is unavailable or throttled, messages remain in the queue until they can be successfully processed, reducing the risk of data loss. There is a Dead Letter Queue (DLQ) attached to the main SQS queue. Attaching a DLQ to SQS ensures that any messages that can’t be processed after multiple attempts are safely captured for inspection and troubleshooting, preventing them from blocking or endlessly circulating in the main queue.
  5. AWS Lambda function reads the messages from SQS queue. Lambda function formats the notification based on your needs.
  6. AWS Lambda publishes the message to Amazon SNS. End users and Central Governance team can subscribe to the SNS topic to receive email alerts when an event happens in SageMaker catalog.
  7. Amazon CloudWatch integrates with AWS Lambda to monitor performance, logs events, and can trigger alarms if anything goes awry, ensuring your workflows run smoothly.

Prerequisites

You need to setup the following prerequisite resources:

  • An AWS account with a configured Amazon Amazon Virtual Private Cloud (Amazon VPC) and base network.
  • An existing SageMaker Unified Studio domain (follow instructions on Setting up Amazon SageMaker Unified Studio).
  • Grant Lambda Access in SageMaker Unified Studio (required for Publishing the assets)
    • Add the Lambda execution role as an IAM role in SageMaker Unified Studio.
    • Assign the Lambda execution role to your project within the SageMaker Unified Studio portal.

This configuration ensures that Lambda function has the required authorization to access Data Zone resources and successfully publish assets from your SageMaker Unified Studio projects.

Code Deployment

Review the instructions on our GitHub repository to deploy the framework in your AWS account using AWS CDK. The CDK provisions an event-driven notification architecture for Amazon SageMaker Unified Studio, focusing on project creation and asset publishing events.

Core AWS Resources Deployed – The following are the core AWS resourced deployed:

  1. EventBridge Rules
    • DataZoneCreateProjectRule: Captures DataZone project creation events (CreateProject).
    • DataZonePublishAssetRule: Captures DataZone asset publishing events (CreateListingChangeSet with PUBLISH action for ASSET entity type).
  2. SQS Queue
    • DataZoneEventQueue: Buffers DataZone events from EventBridge before processing.
    • Queue Policy: Allows EventBridge to send messages to the SQS queue.
  3. Lambda Function
    • ProjectNotificationLambda: Processes messages from the SQS queue, retrieves event details from DataZone, and sends notifications to an SNS topic.
      • IAM Role: Grants permissions to access SQS, SNS, CloudWatch Logs, and DataZone services.
      • Event Source Mapping: Triggers the Lambda function for each SQS message.
  4. SNS Topic
    • LambdaSNSTopic: Receives notifications from the Lambda function.
      • Email Subscriptions: Two email endpoints are subscribed to receive notifications.
    • Add your email ID to the SNS topic. You’ll receive an email to request for subscription, click on ‘Confirm Subscription’
  5. Permissions
    • Amazon EventBridge sends events to SQS (requiring SQS permissions), Lambda poll reads messages from Amazon SQS (requiring Lambda role in SQS permissions), and Lambda publishes to Amazon SNS (requiring SNS permissions).
    • IAM Policies: Lambda execution role has necessary permissions for SQS, SNS, logging, and Data Zone operations.

Outputs Provided (CloudFormation Output)

  • Amazon SNS Topic ARN: For notification publishing.
  • Amazon SQS Queue ARN: For event buffering.
  • AWS Lambda Function ARN: For event processing.
  • Amazon EventBridge Rule ARNs: For both asset publishing and project creation events.

Project Creation Notification

Execute the following steps to login to SageMaker Unified Studio and create a project.

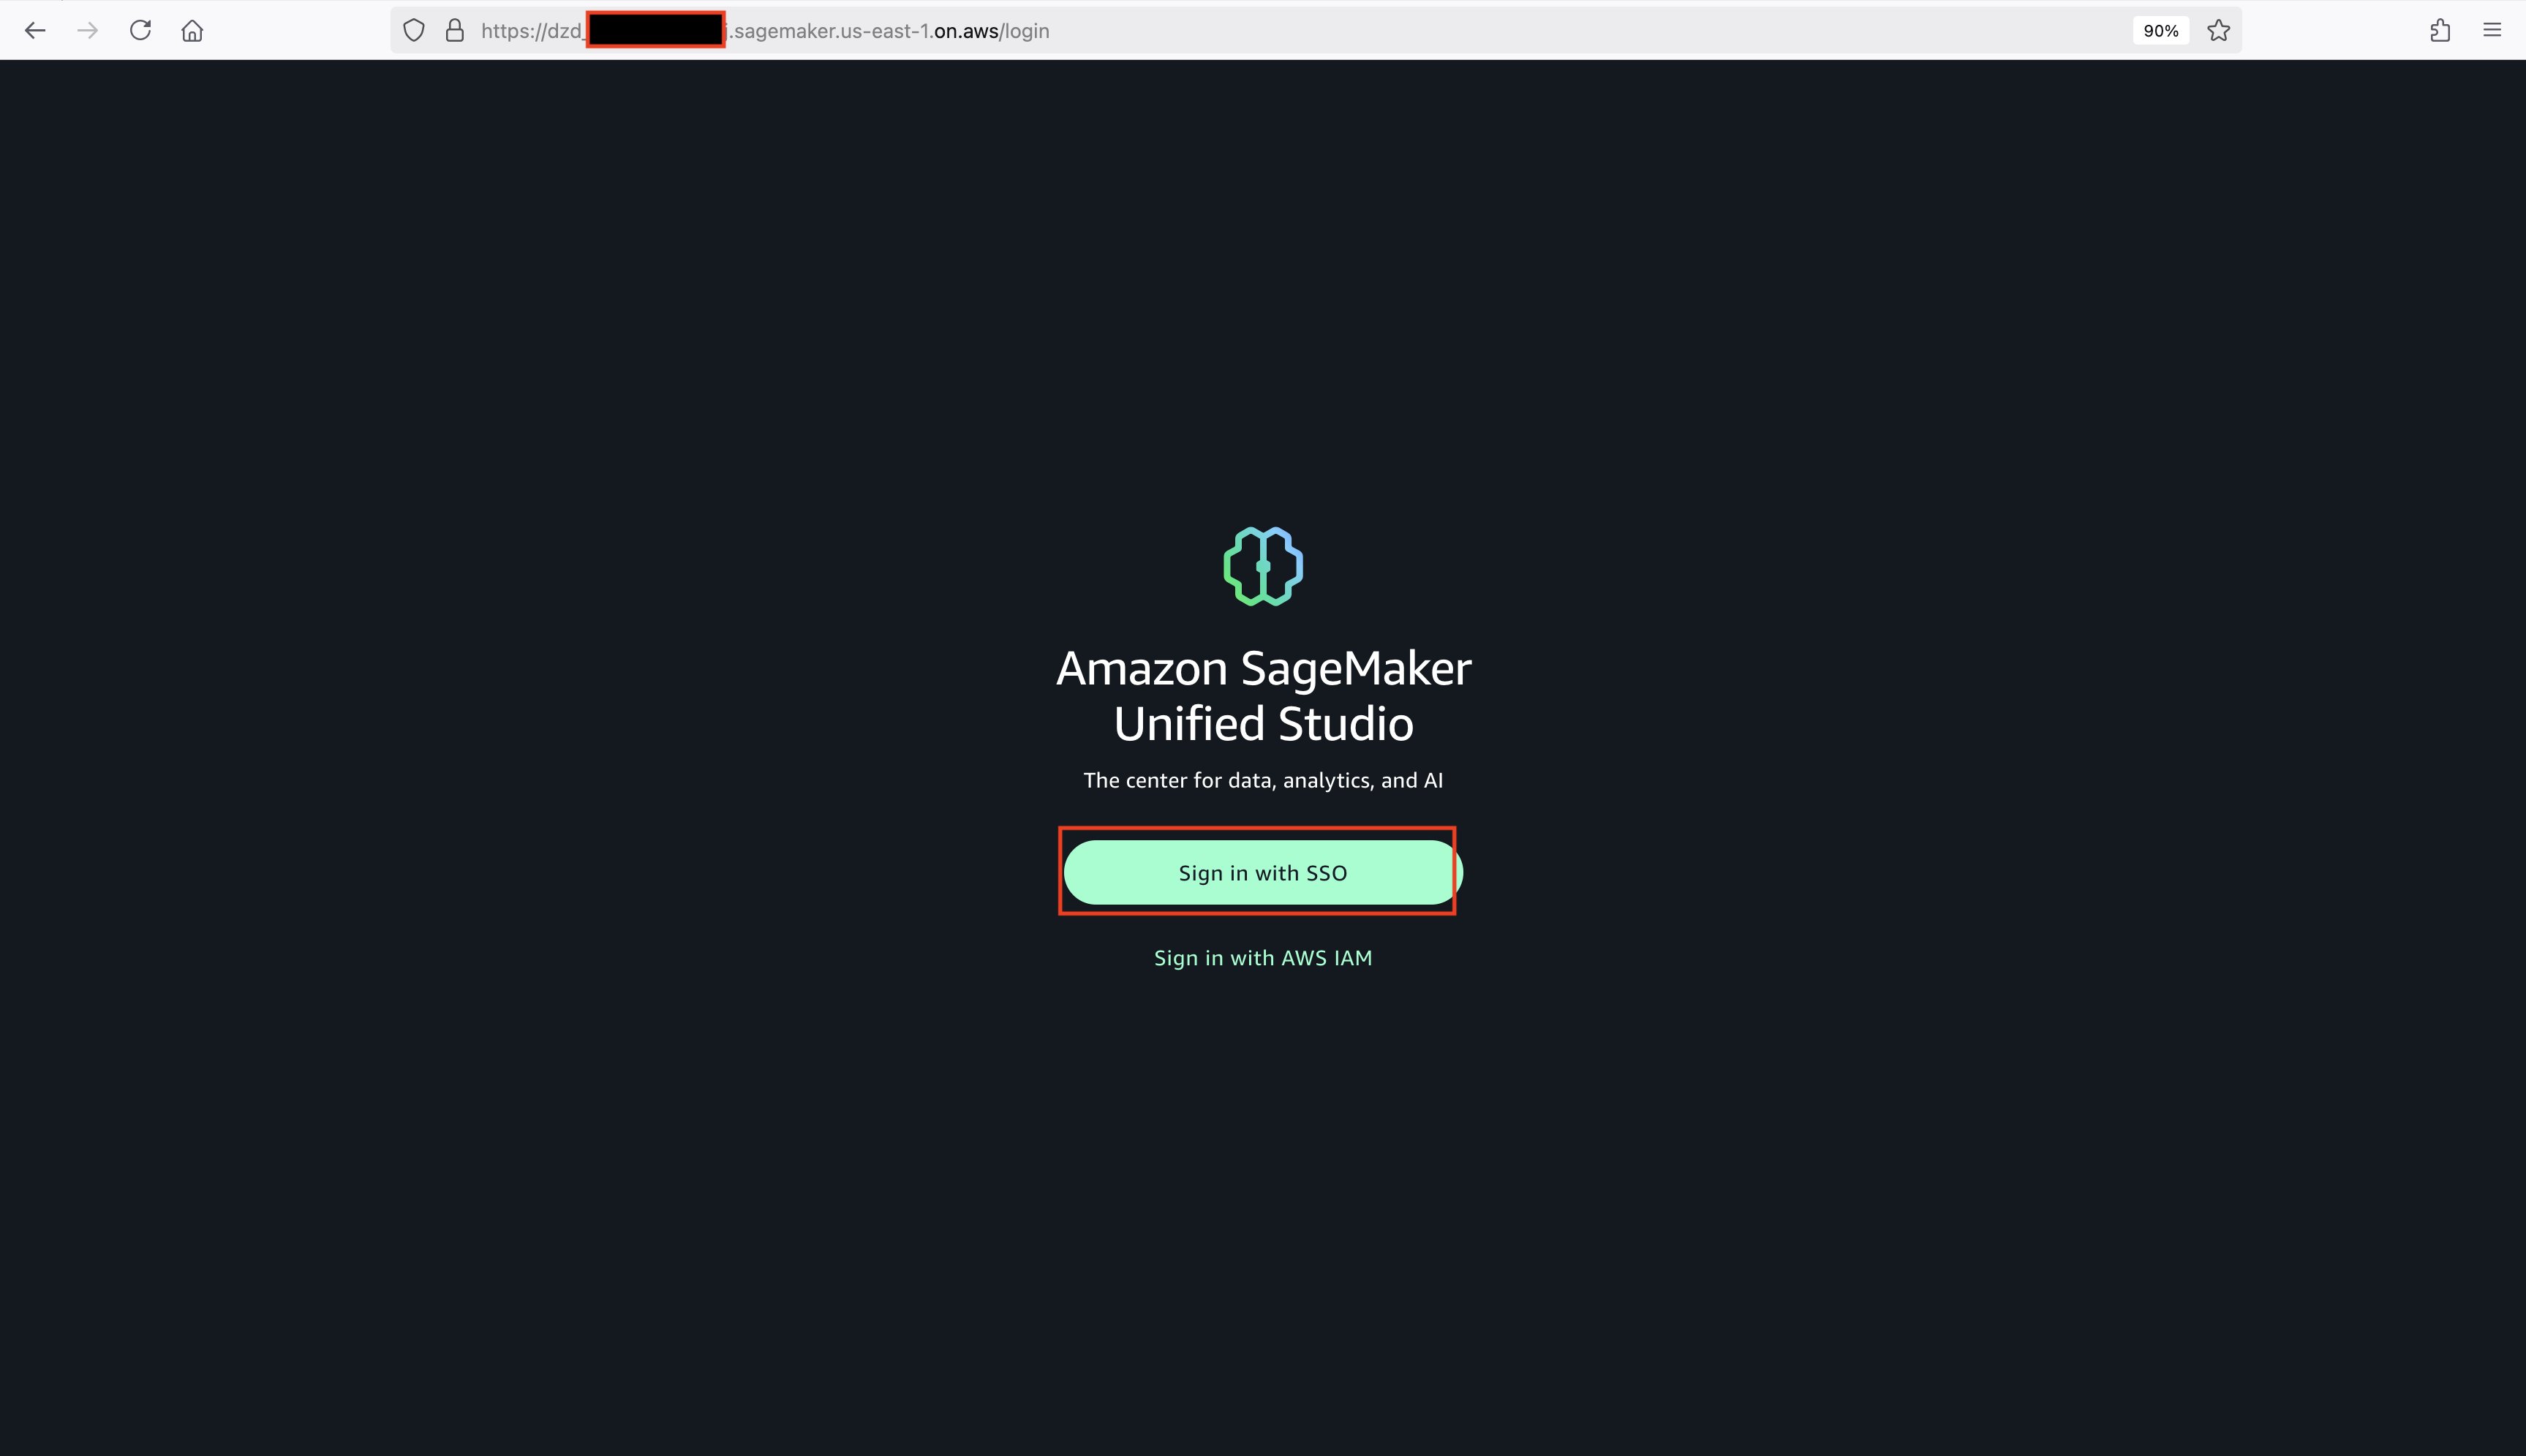
  1. Login to SageMaker Unified Studio Console. This takes you to Amazon SageMaker Unified Studio domain login screen (SSO and IAM sign-in options).
    SageMaker Unified Studio Login
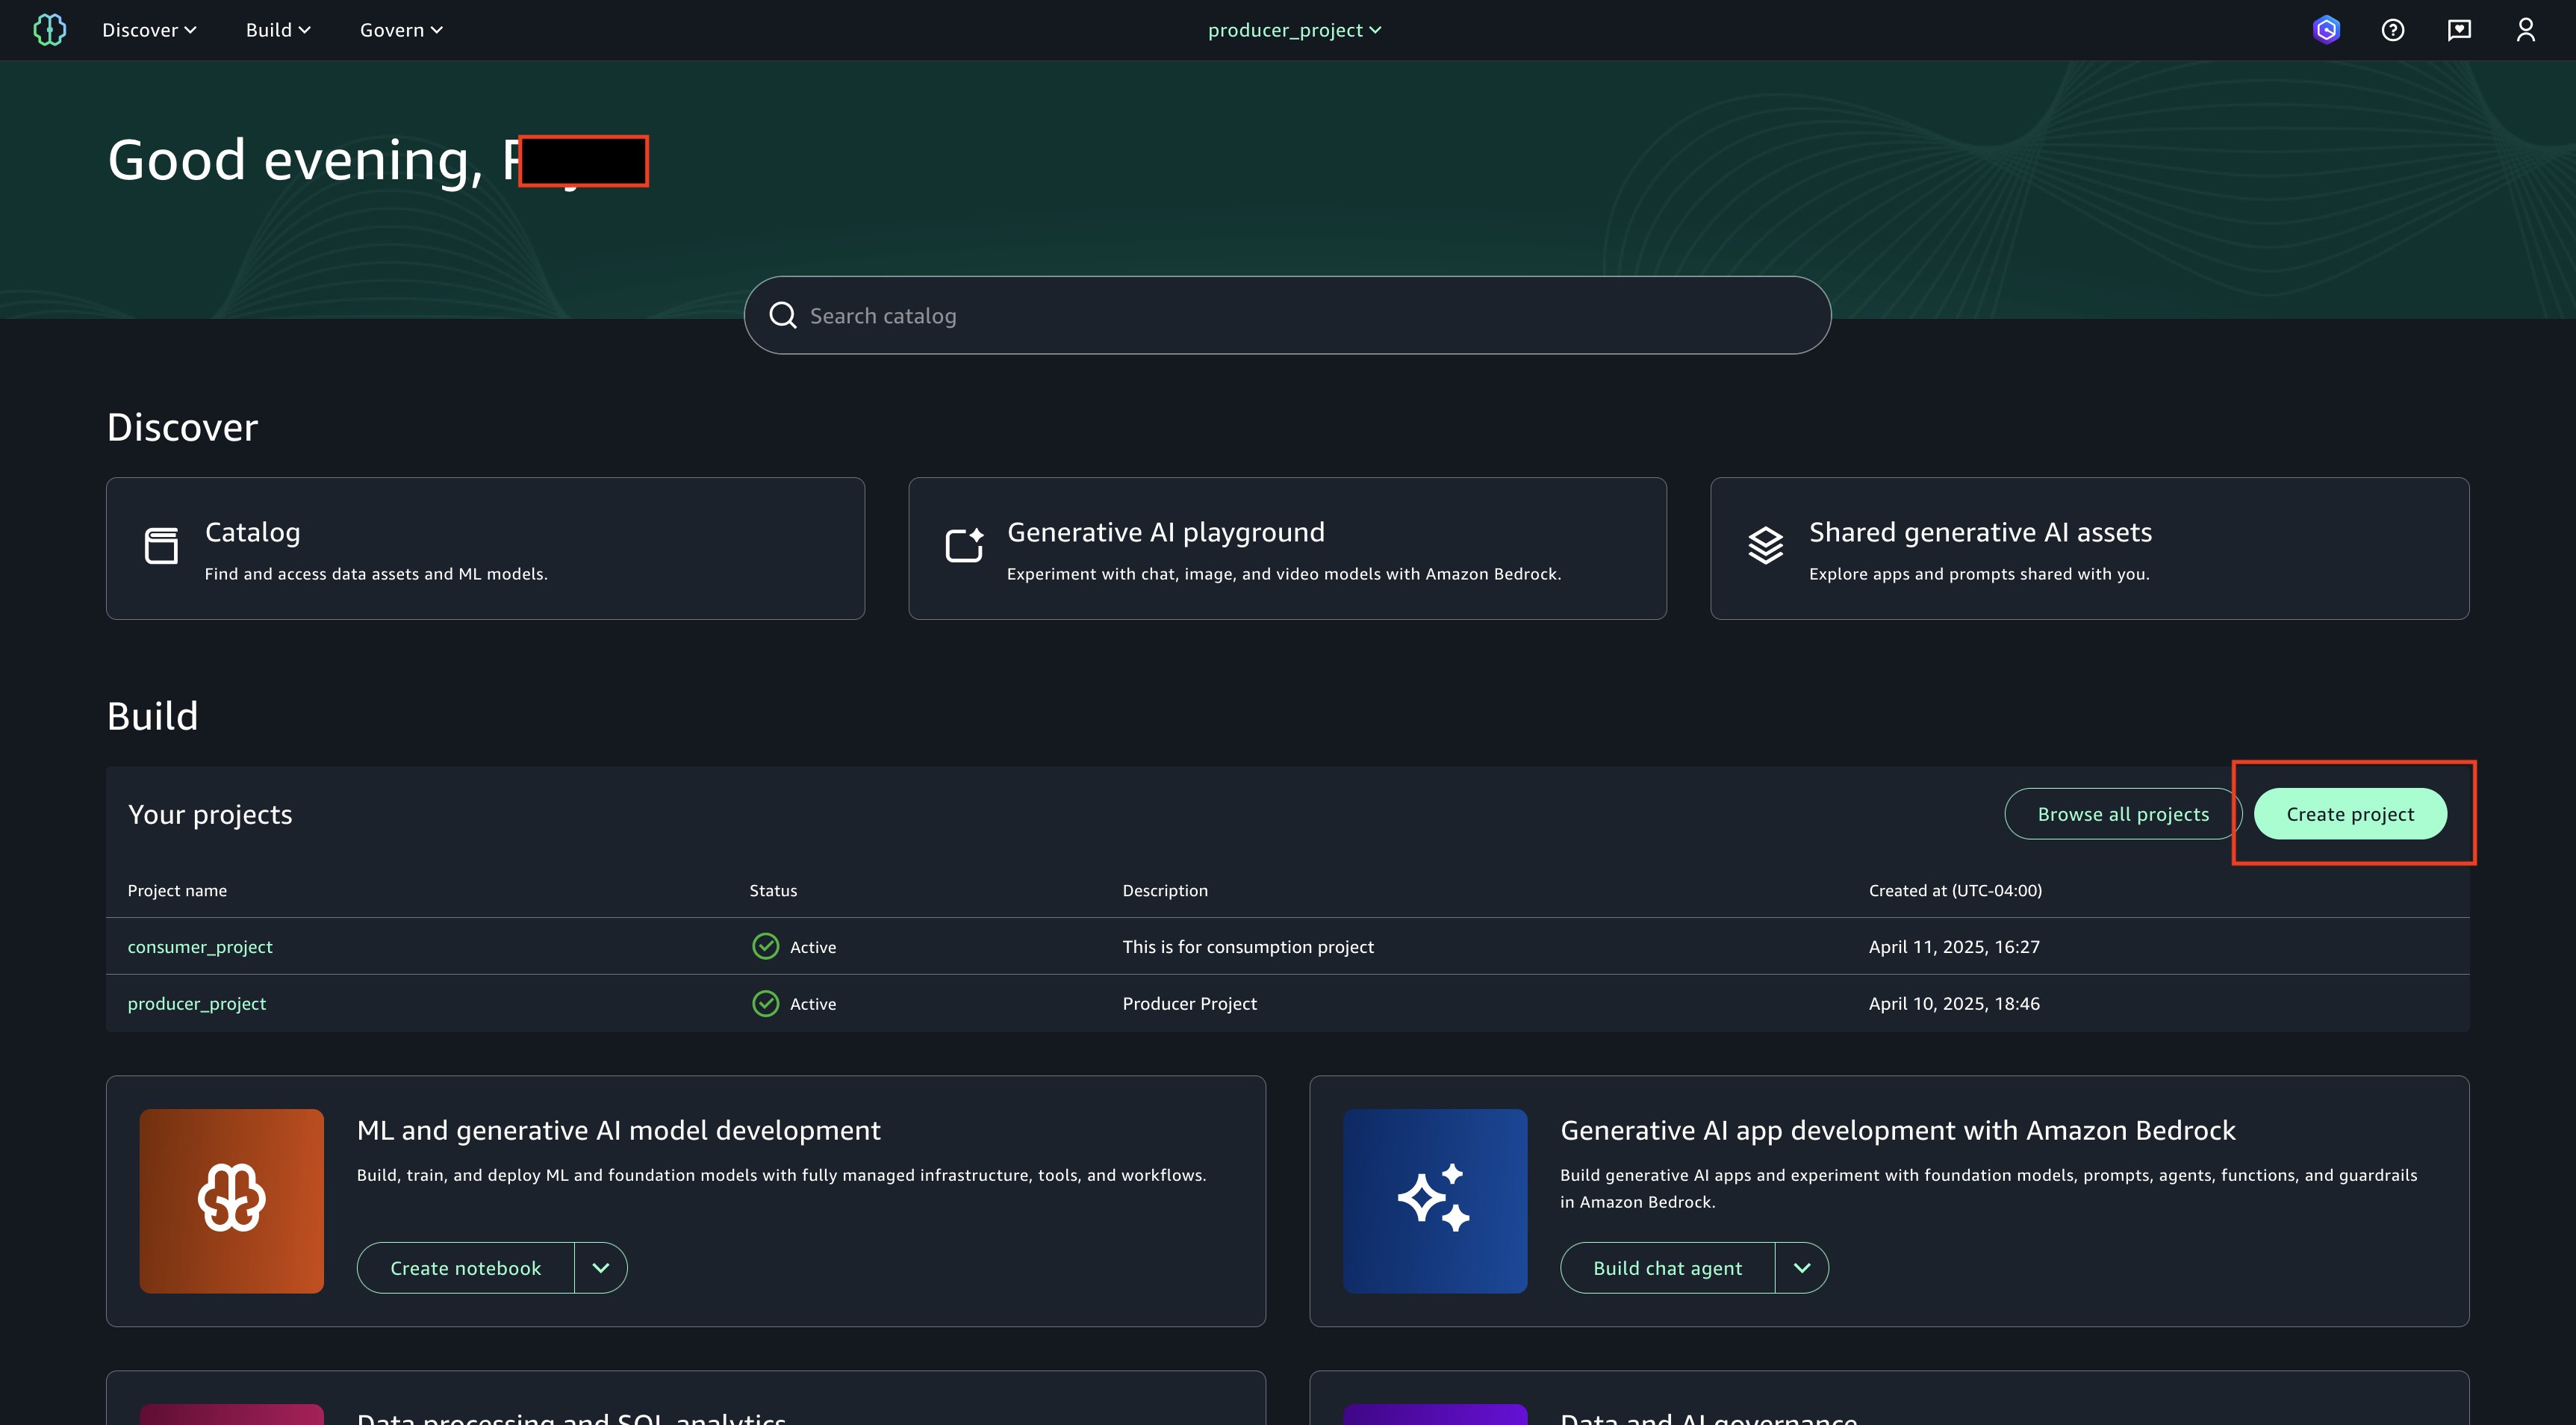
  2. Choose Create Project on SageMaker Unified Studio login page.
    Create Project
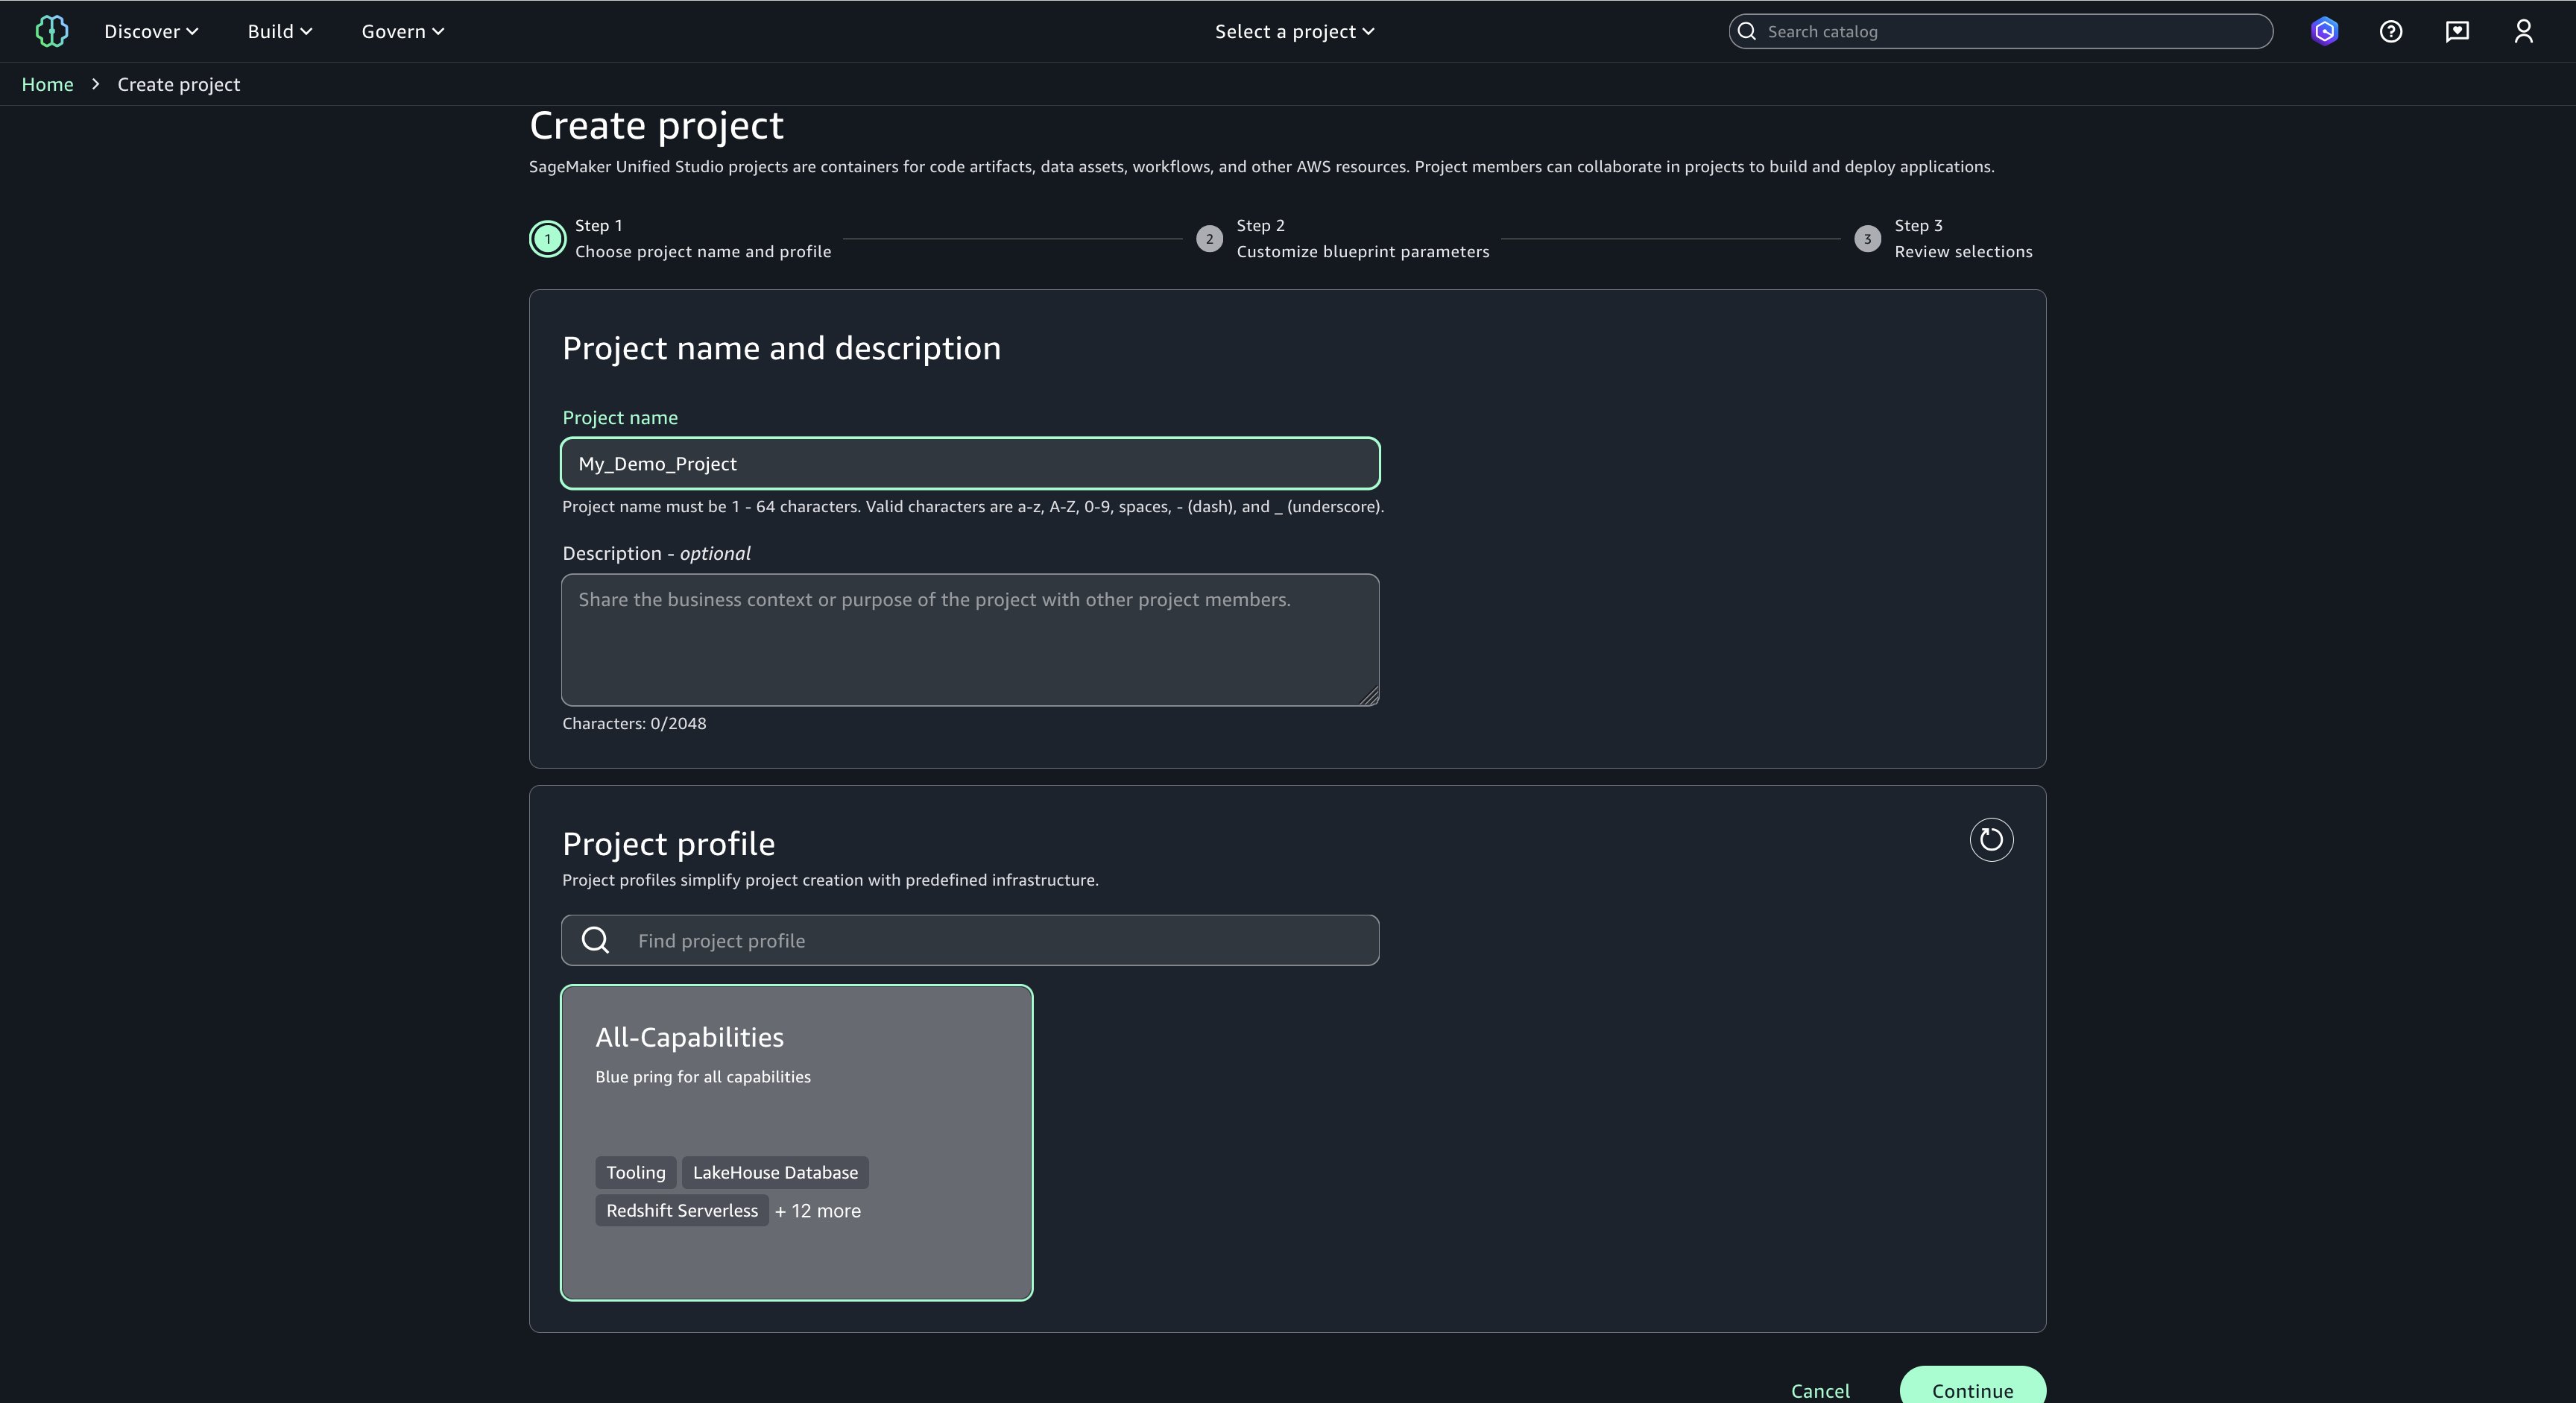
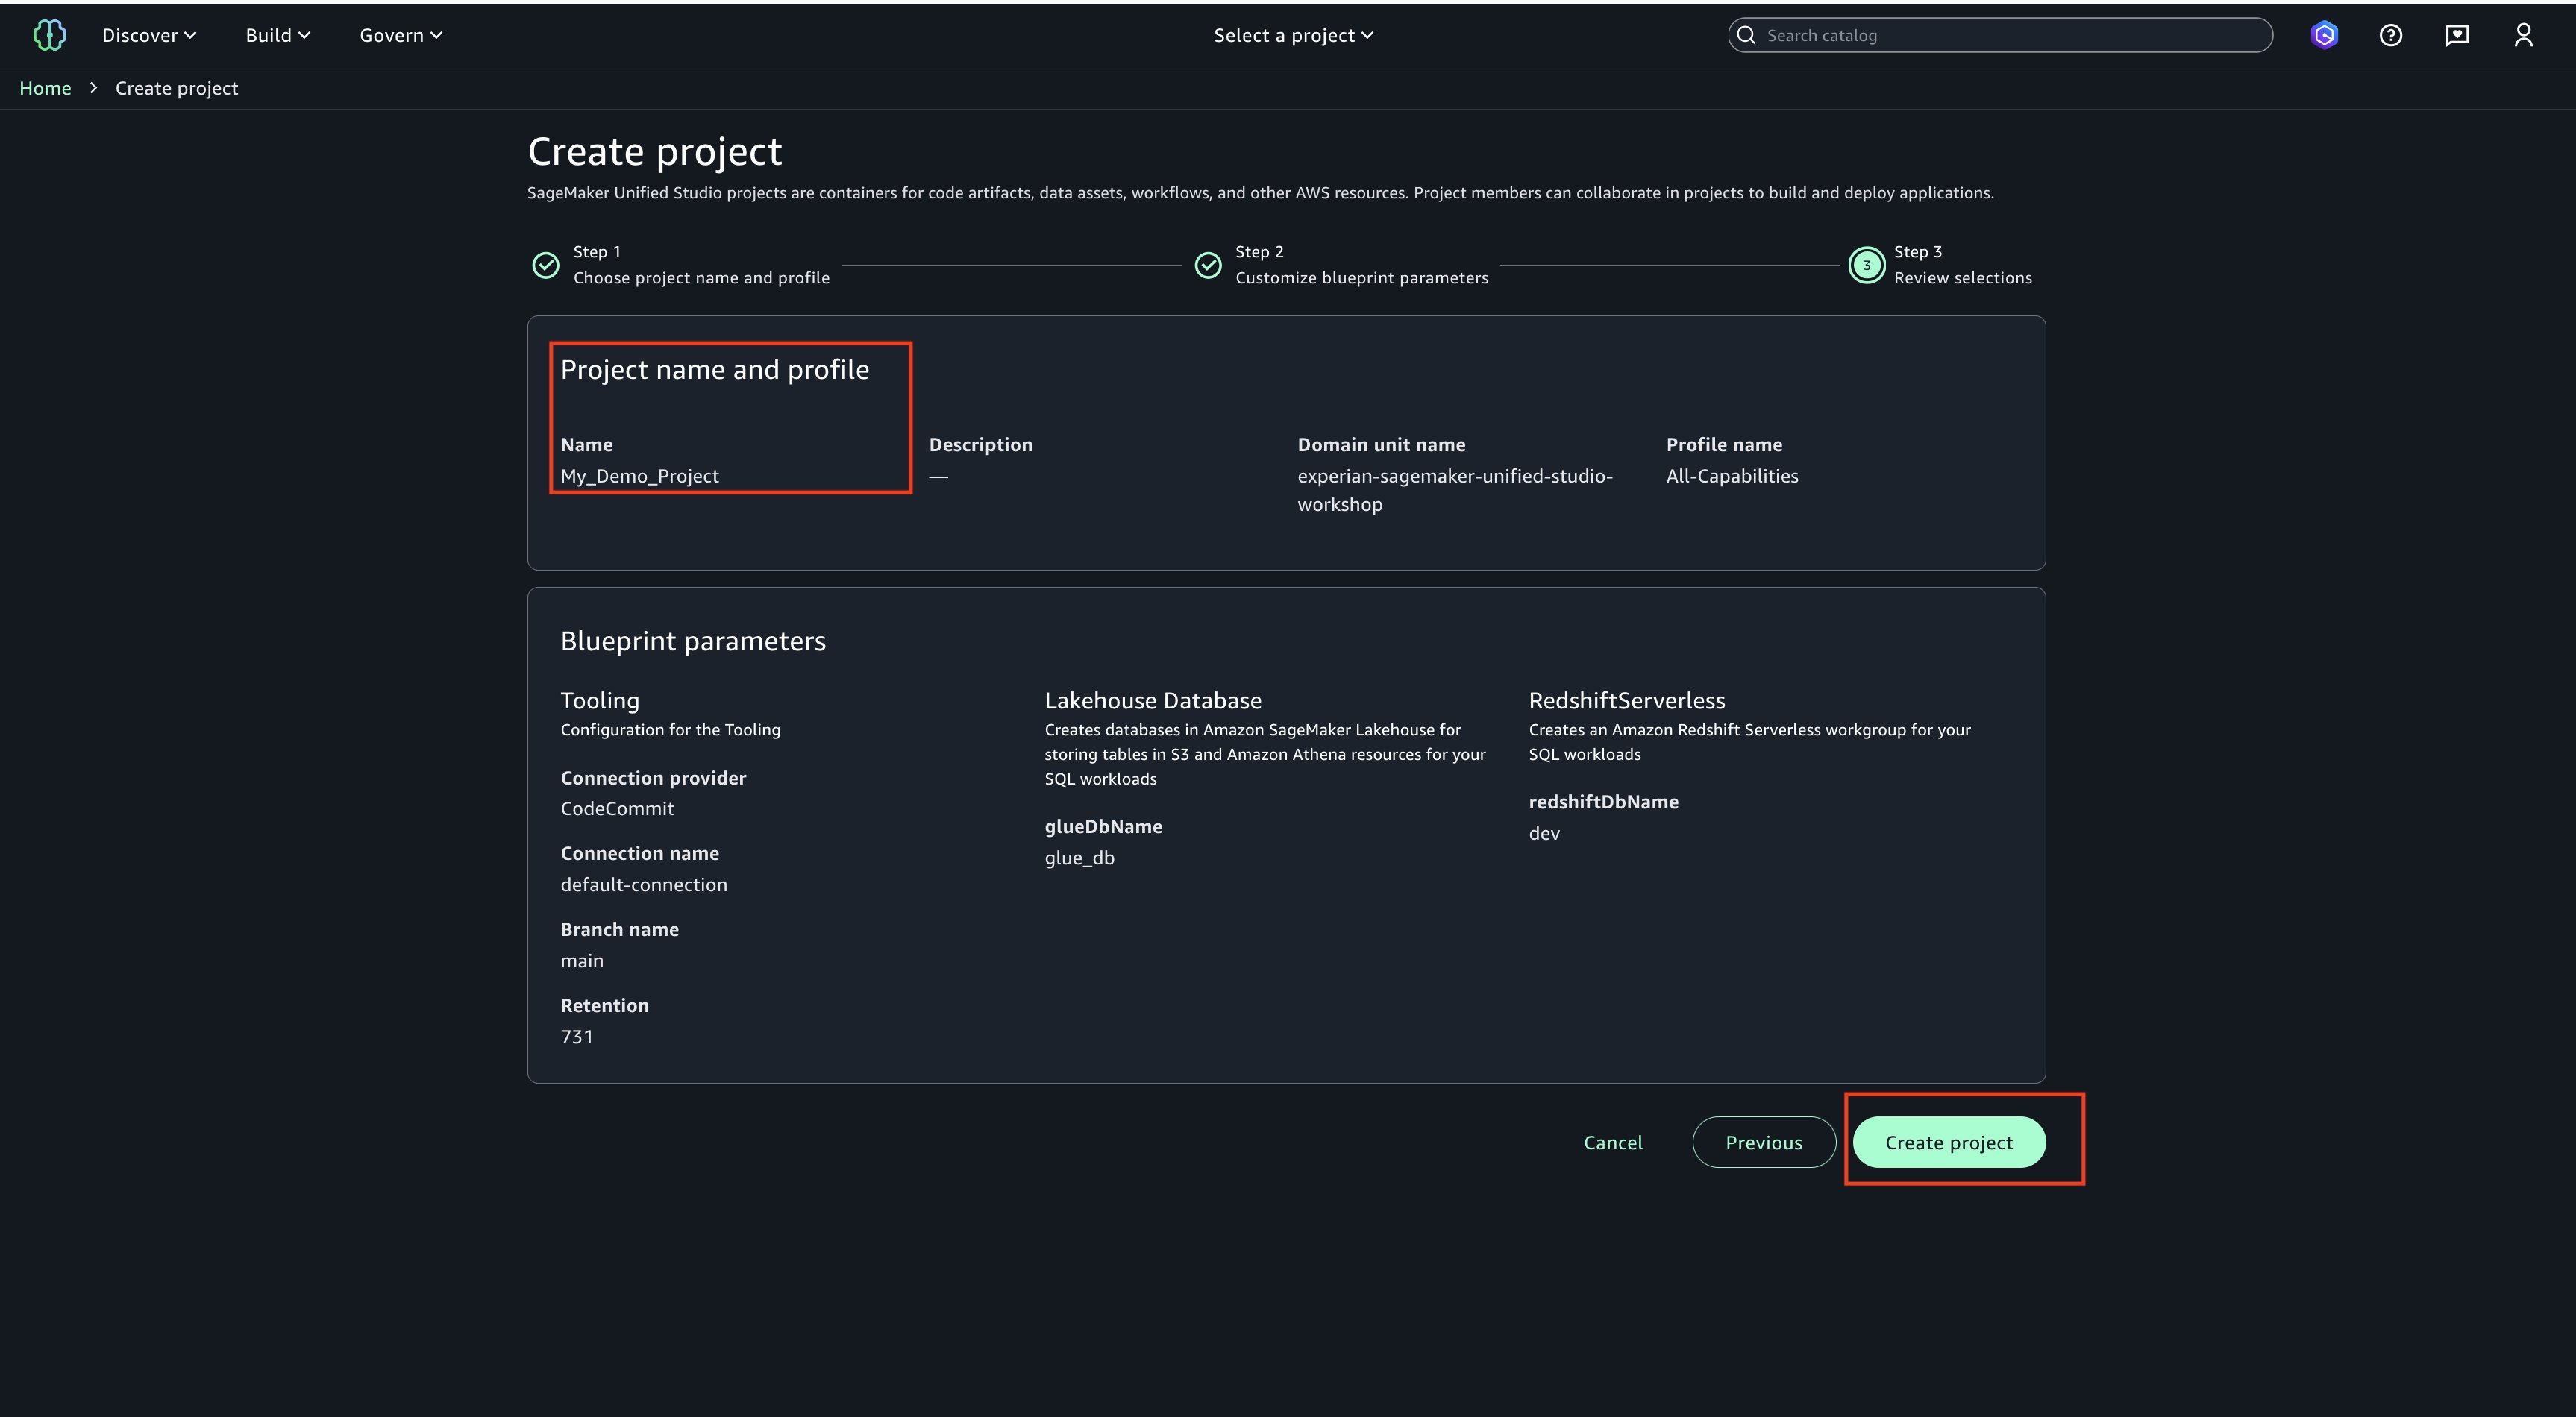
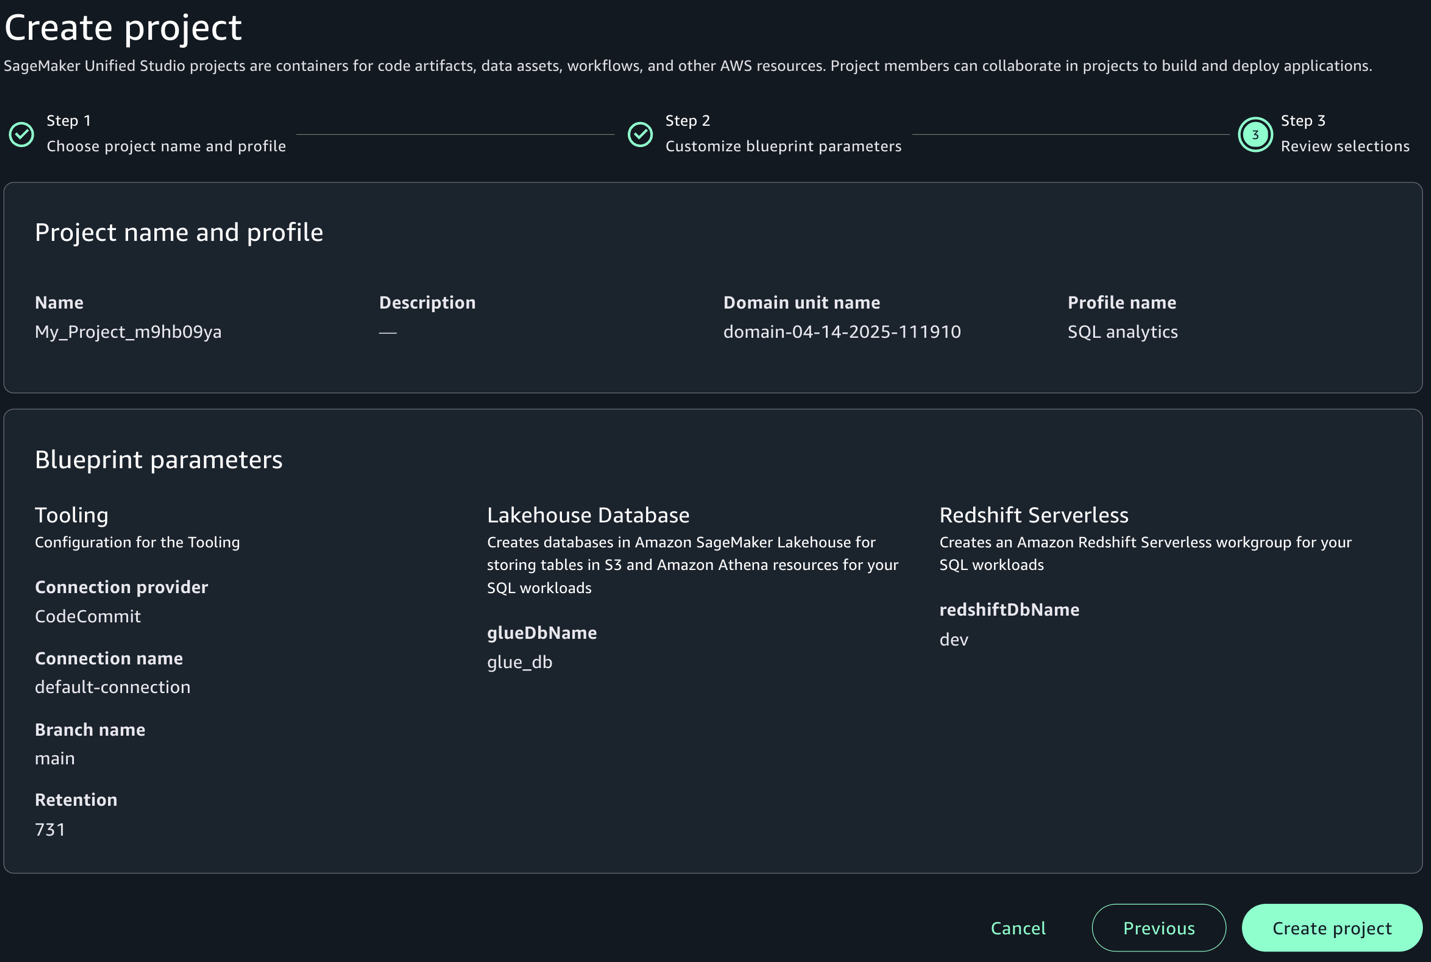
  3. Choose a project name of your choice, such as ‘My_Demo_Project’. In Project profile, select ‘All-Capabilities’.
    Demo Project
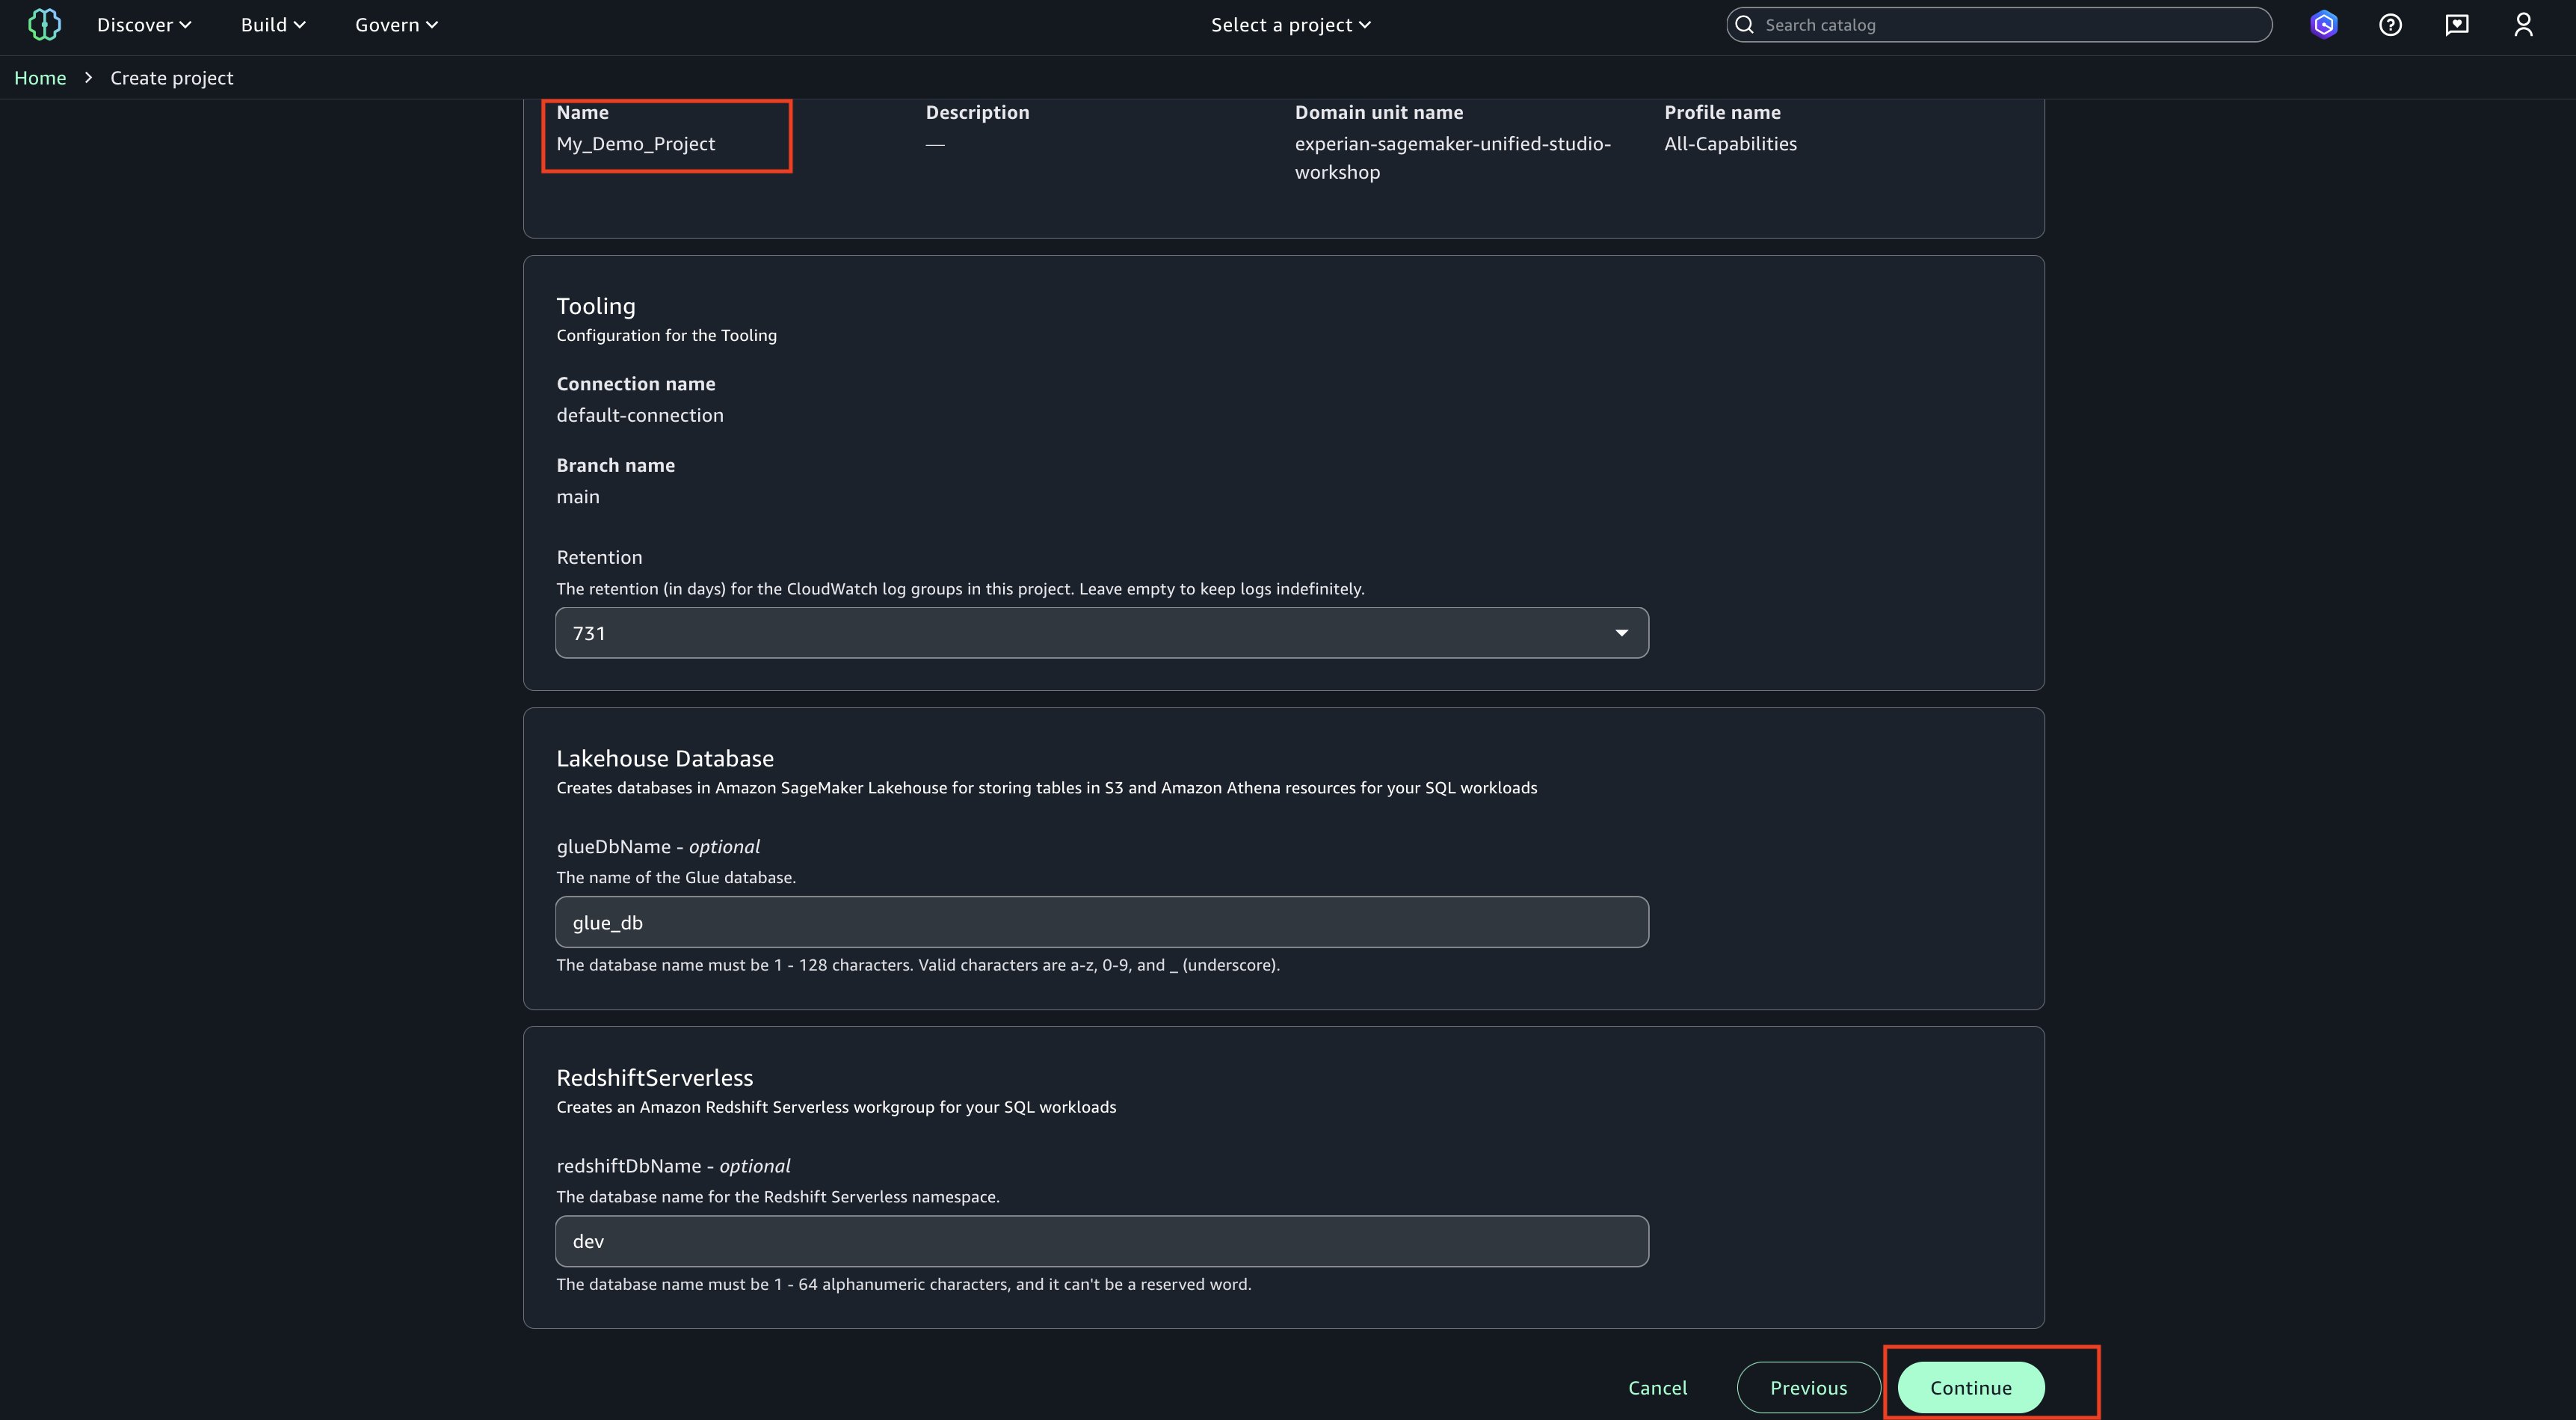
  4. Choose Continue. Keep everything as default.
  5. Choose Continue. On next page, create on ‘Create project’.
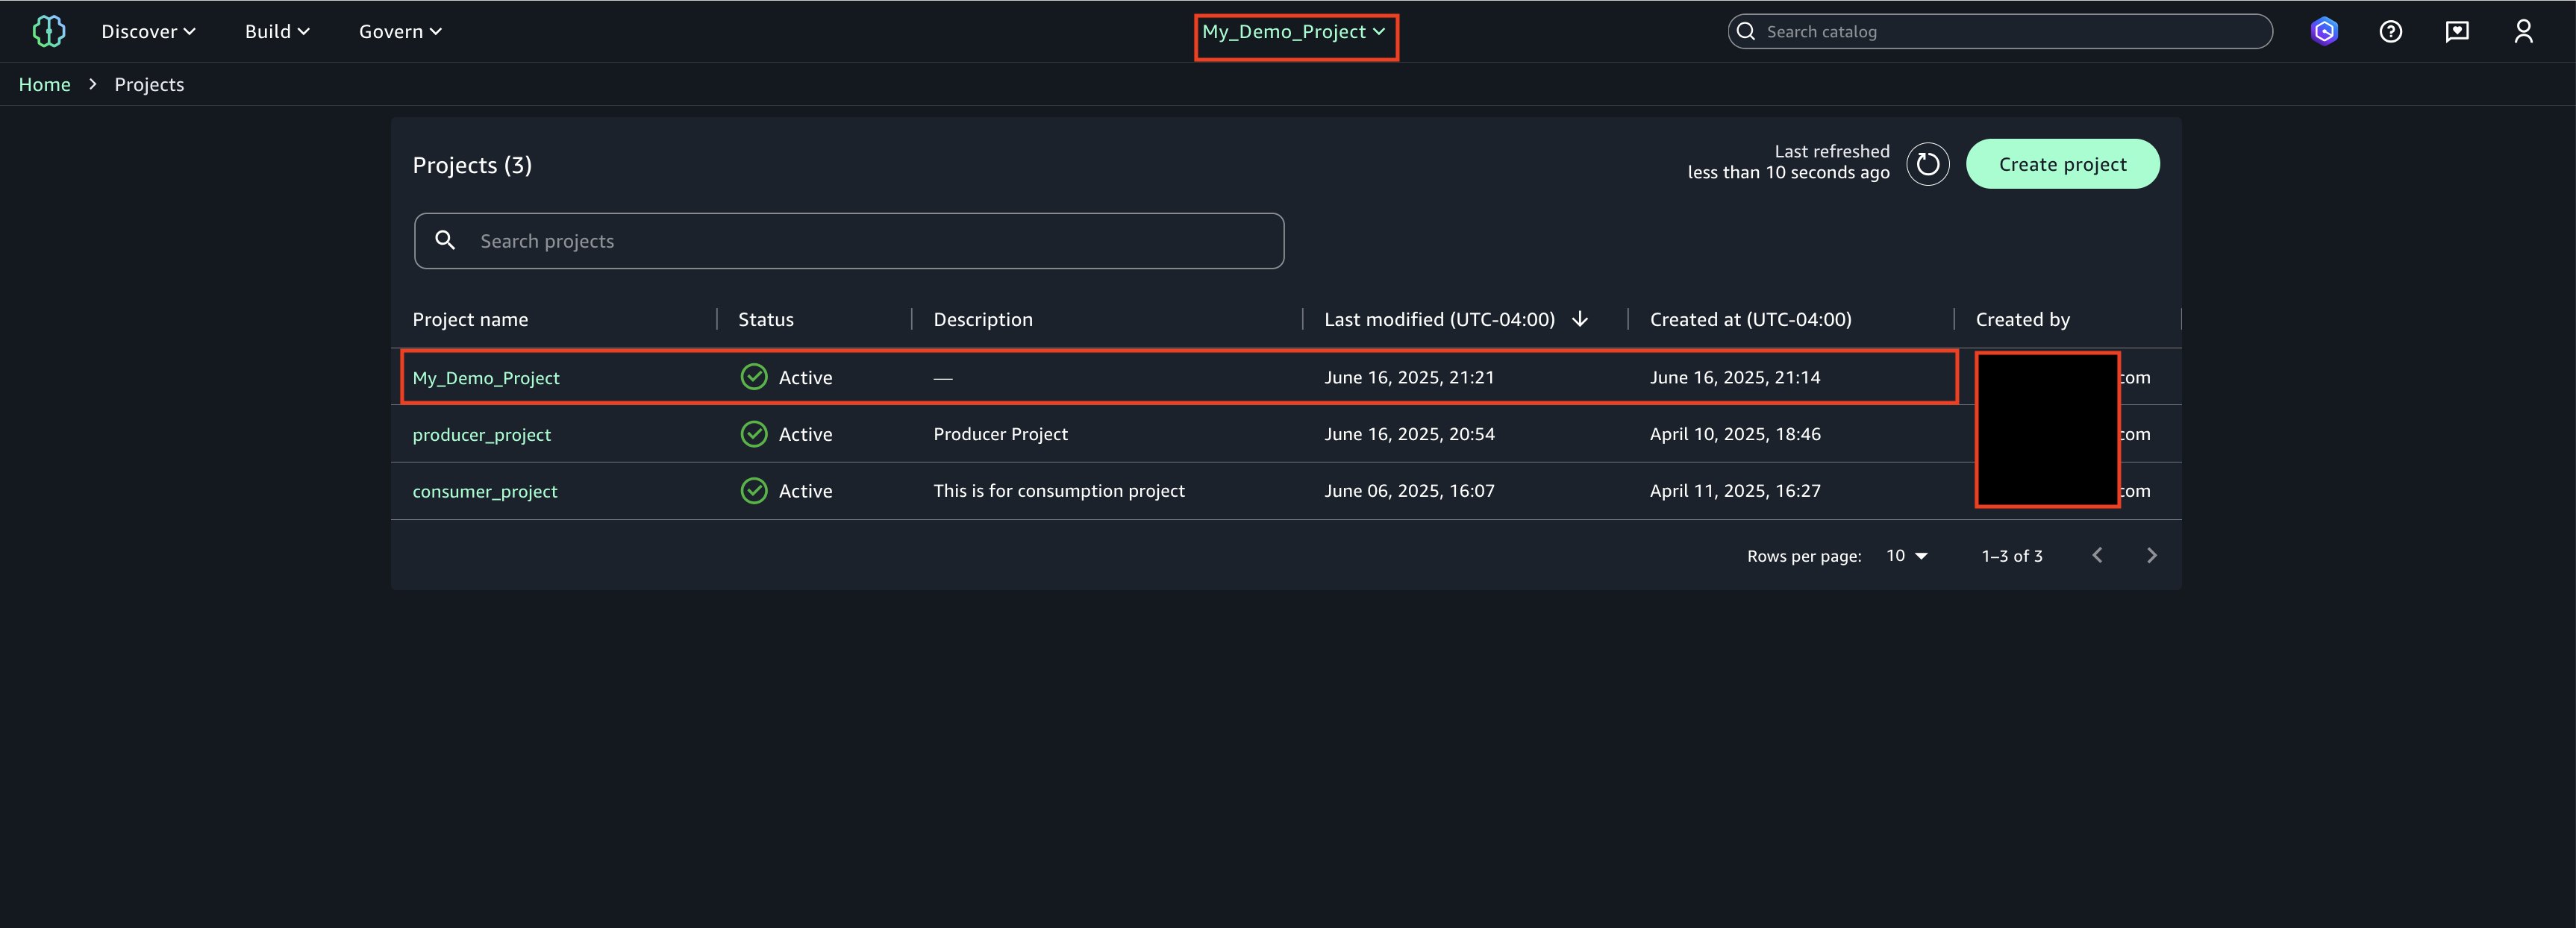
  6. Project creation final screen
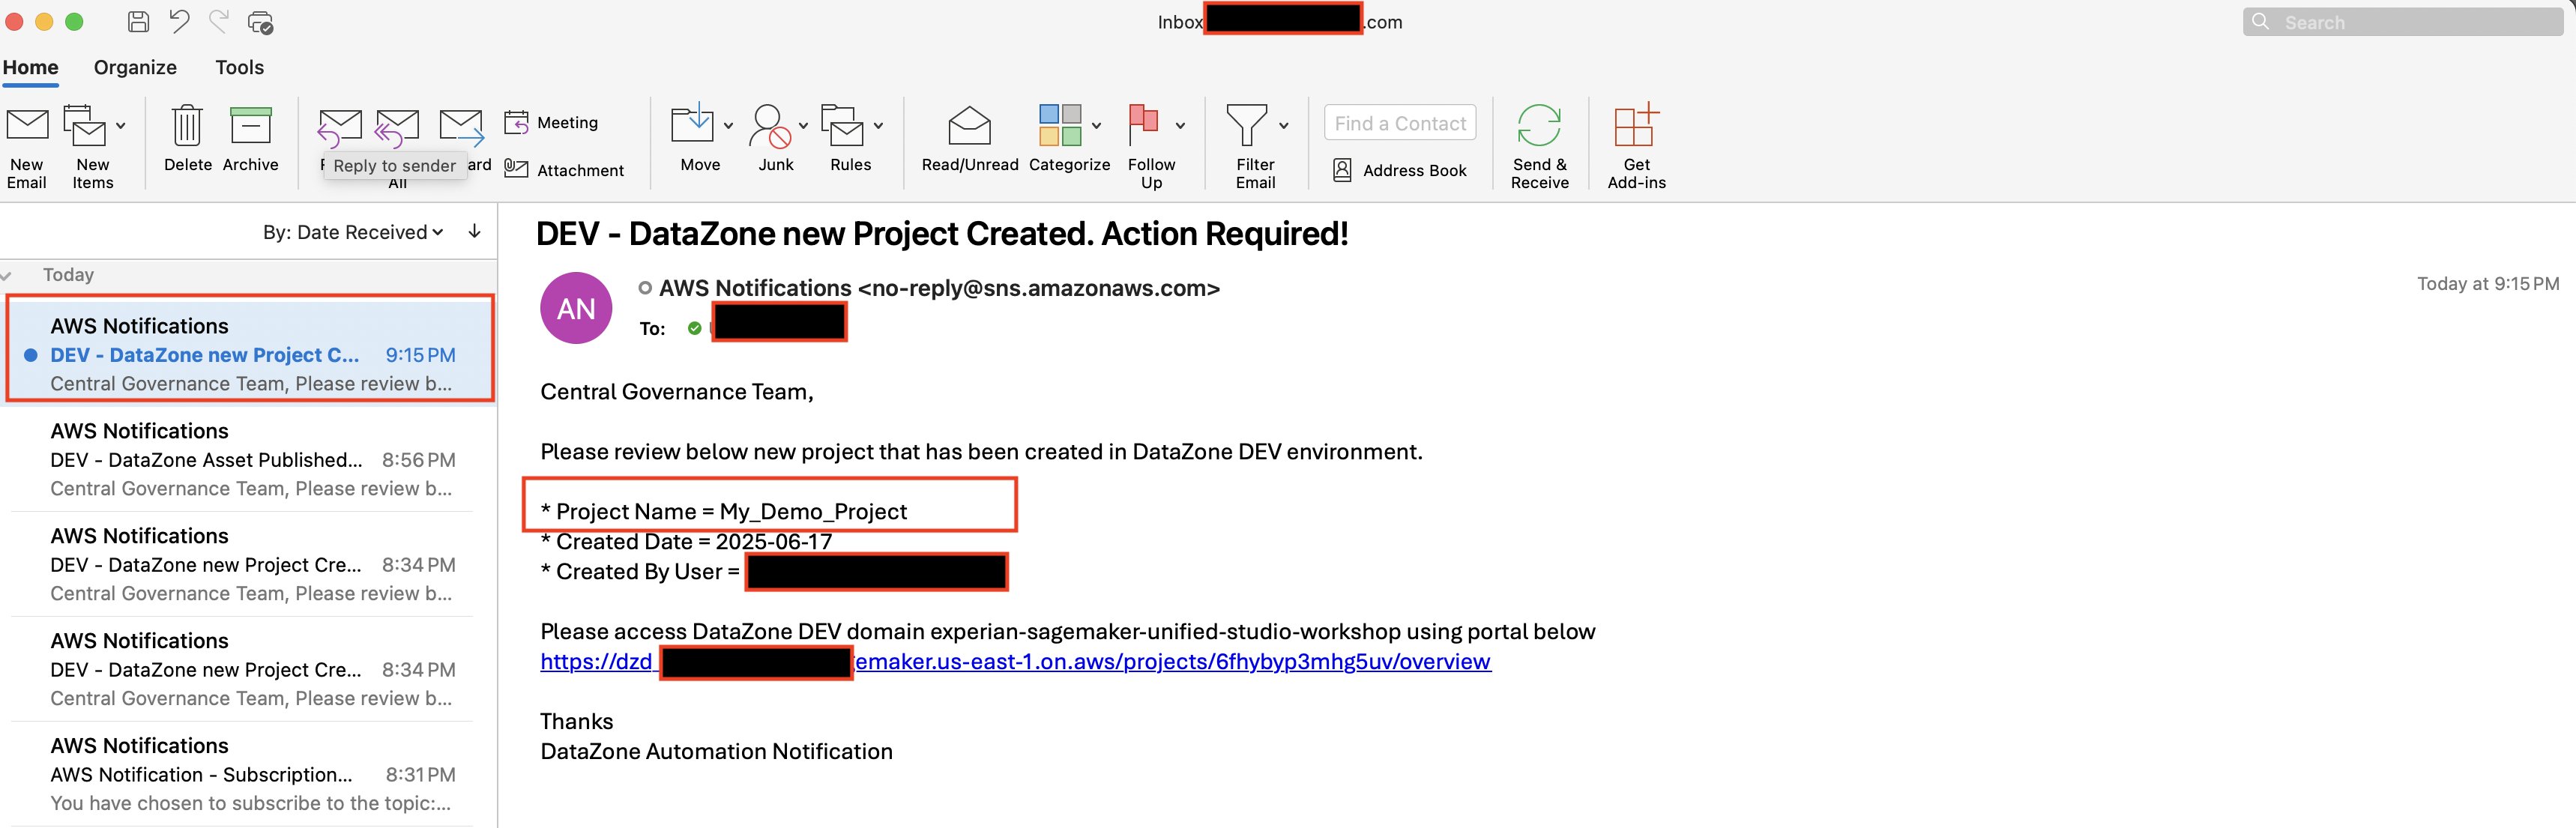
  7. Email Notification. Once project creation is successful, you should see an email notification sent by the above deployed automation.

Asset Publish Notification

To publish a sample asset in SageMaker Unified Studio.

  1. Lambda Permissions
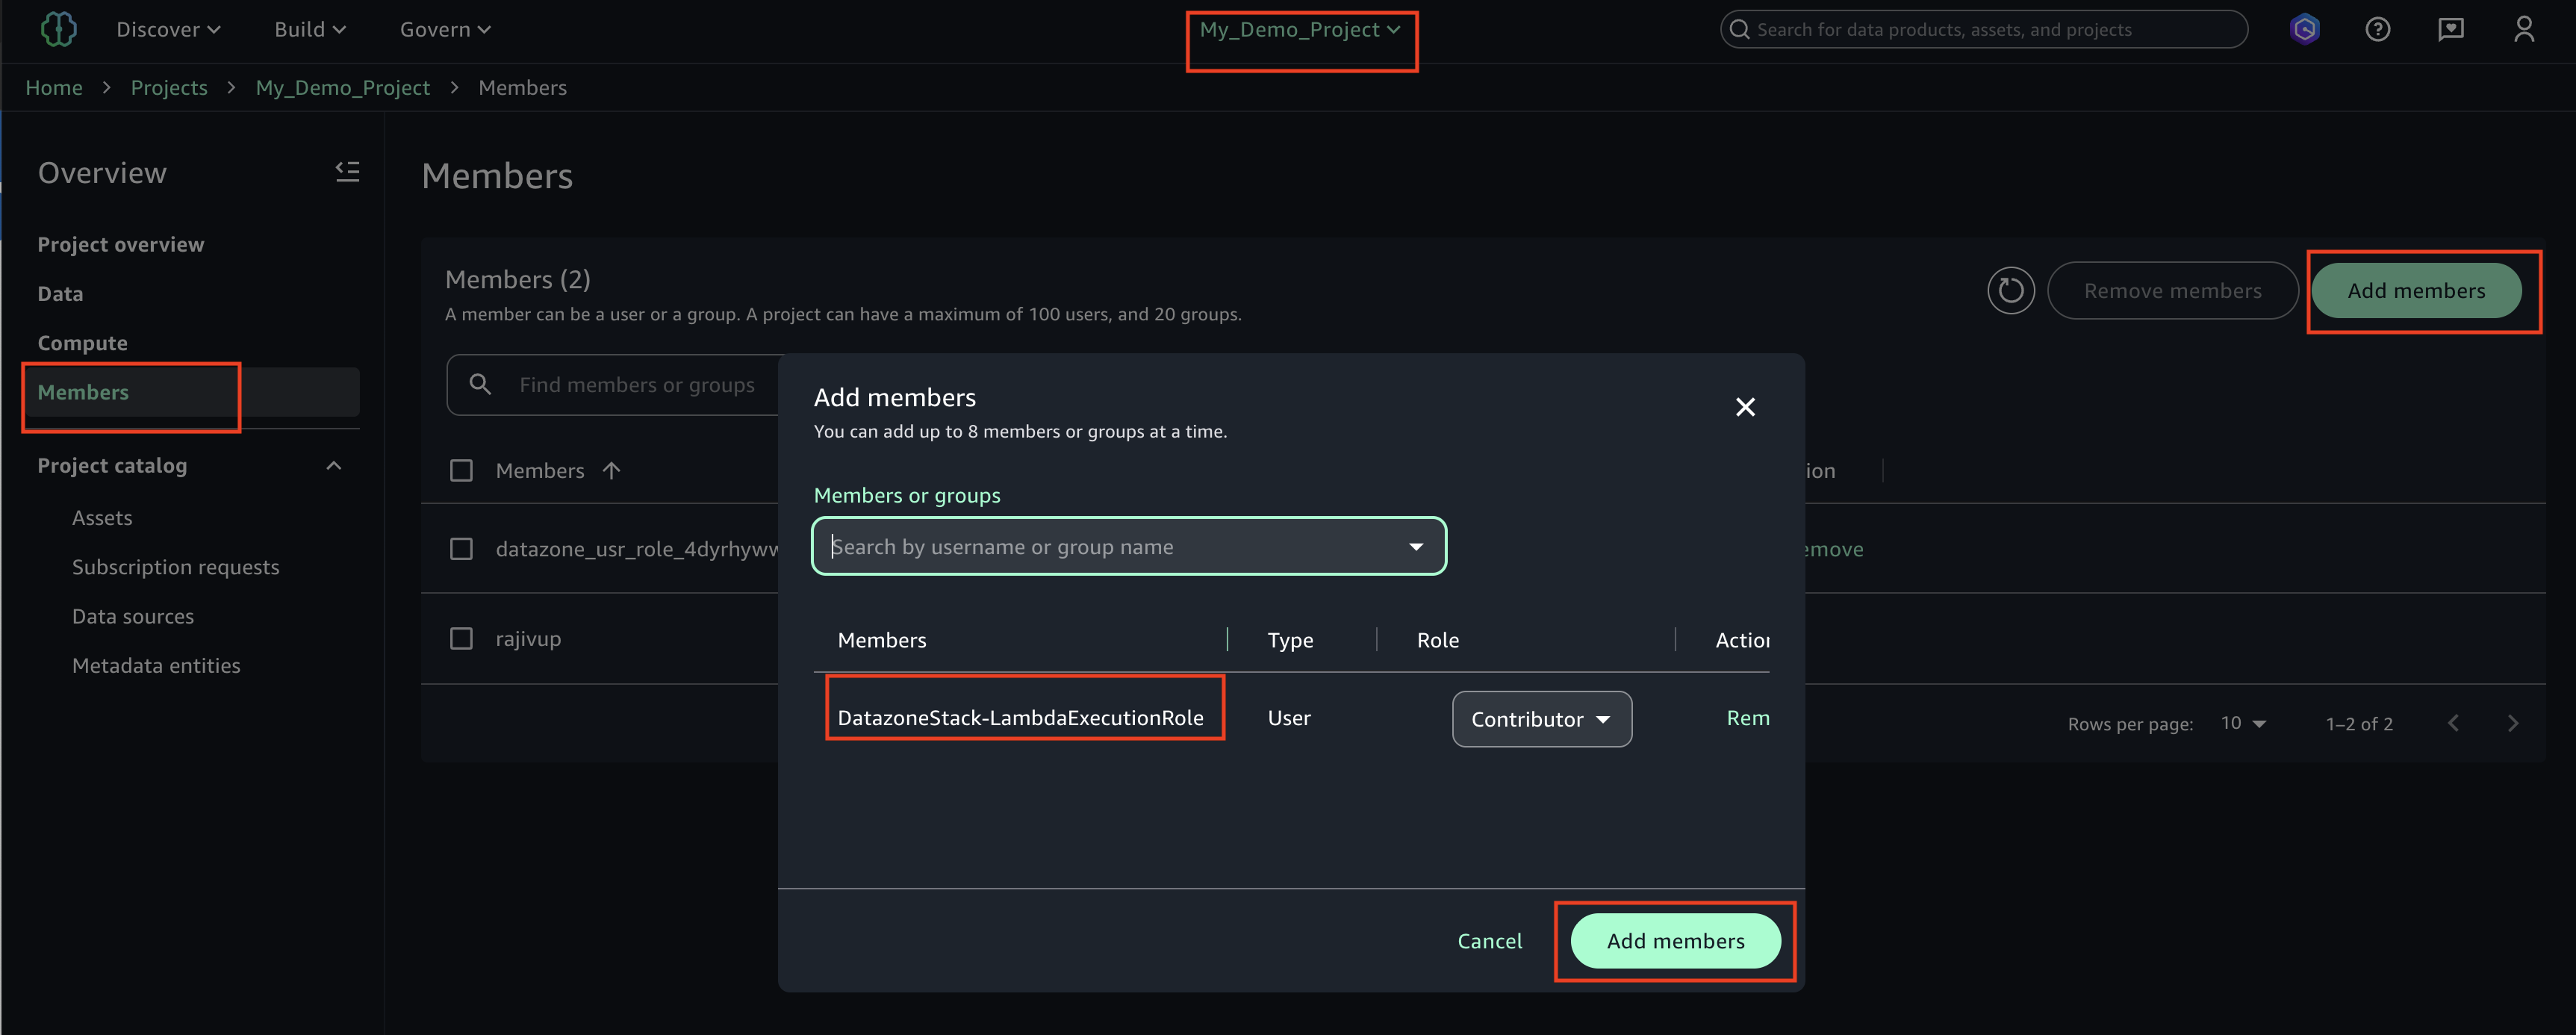
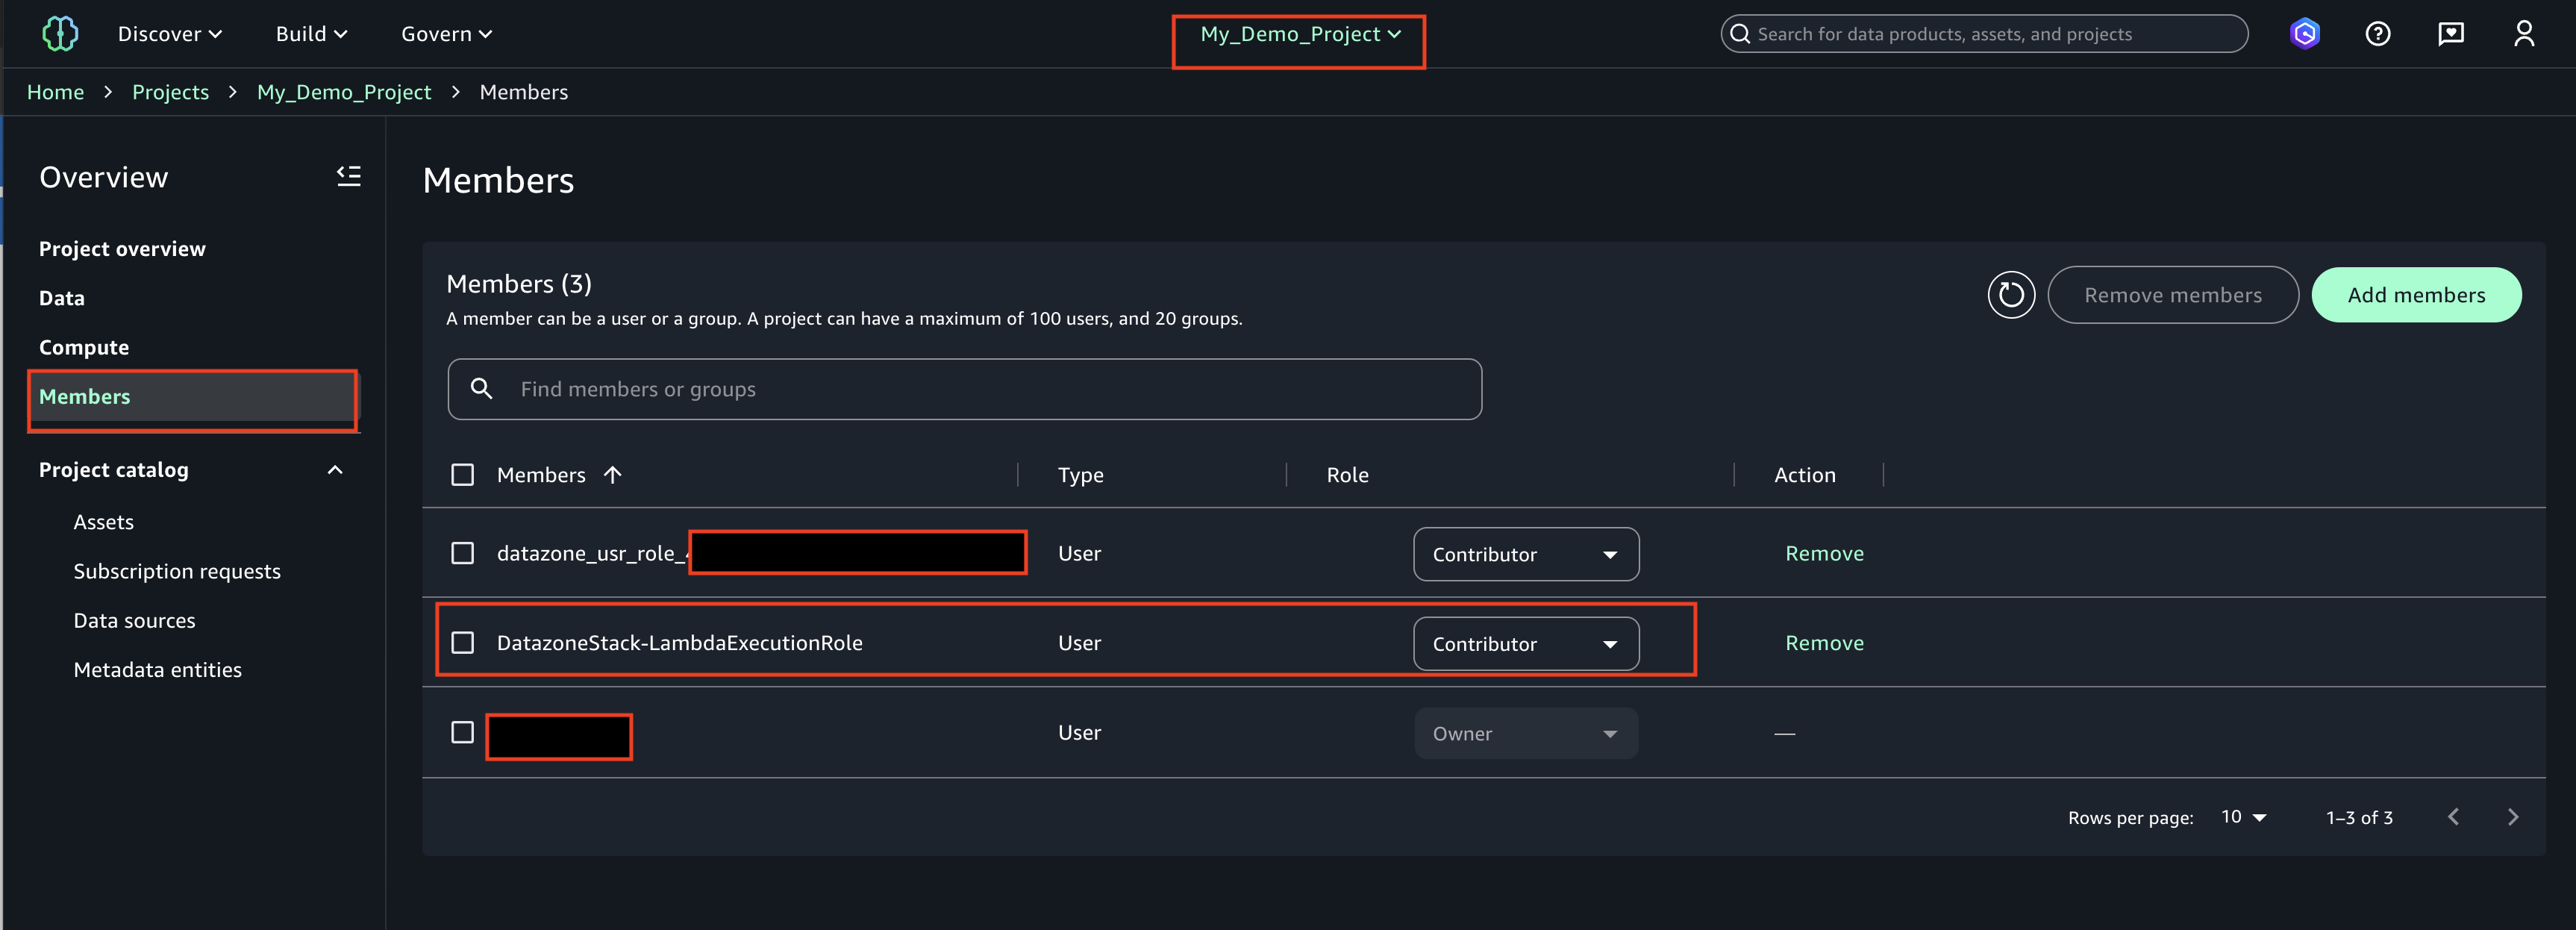
    After the CDK Stack creates the Lambda execution role ‘DatazoneStack-LambdaExecutionRole’, use the following procedure to integrate this role into your SageMaker Studio project. This integration enables Lambda functions to interact with DataZone API in SageMaker Unified Studio project.

    1. Login to SageMaker Unified studio using SSO, click on Members, Add members.
    2. Find the role ‘DatazoneStack-LambdaExecutionRole’ and add as a ‘Contributor’

      The LambdaExecutionRole (<cf-stack-name>-LambdaExecutionRole) has been added as a member to a project in SageMaker Unified Studio.

  2. Create Asset
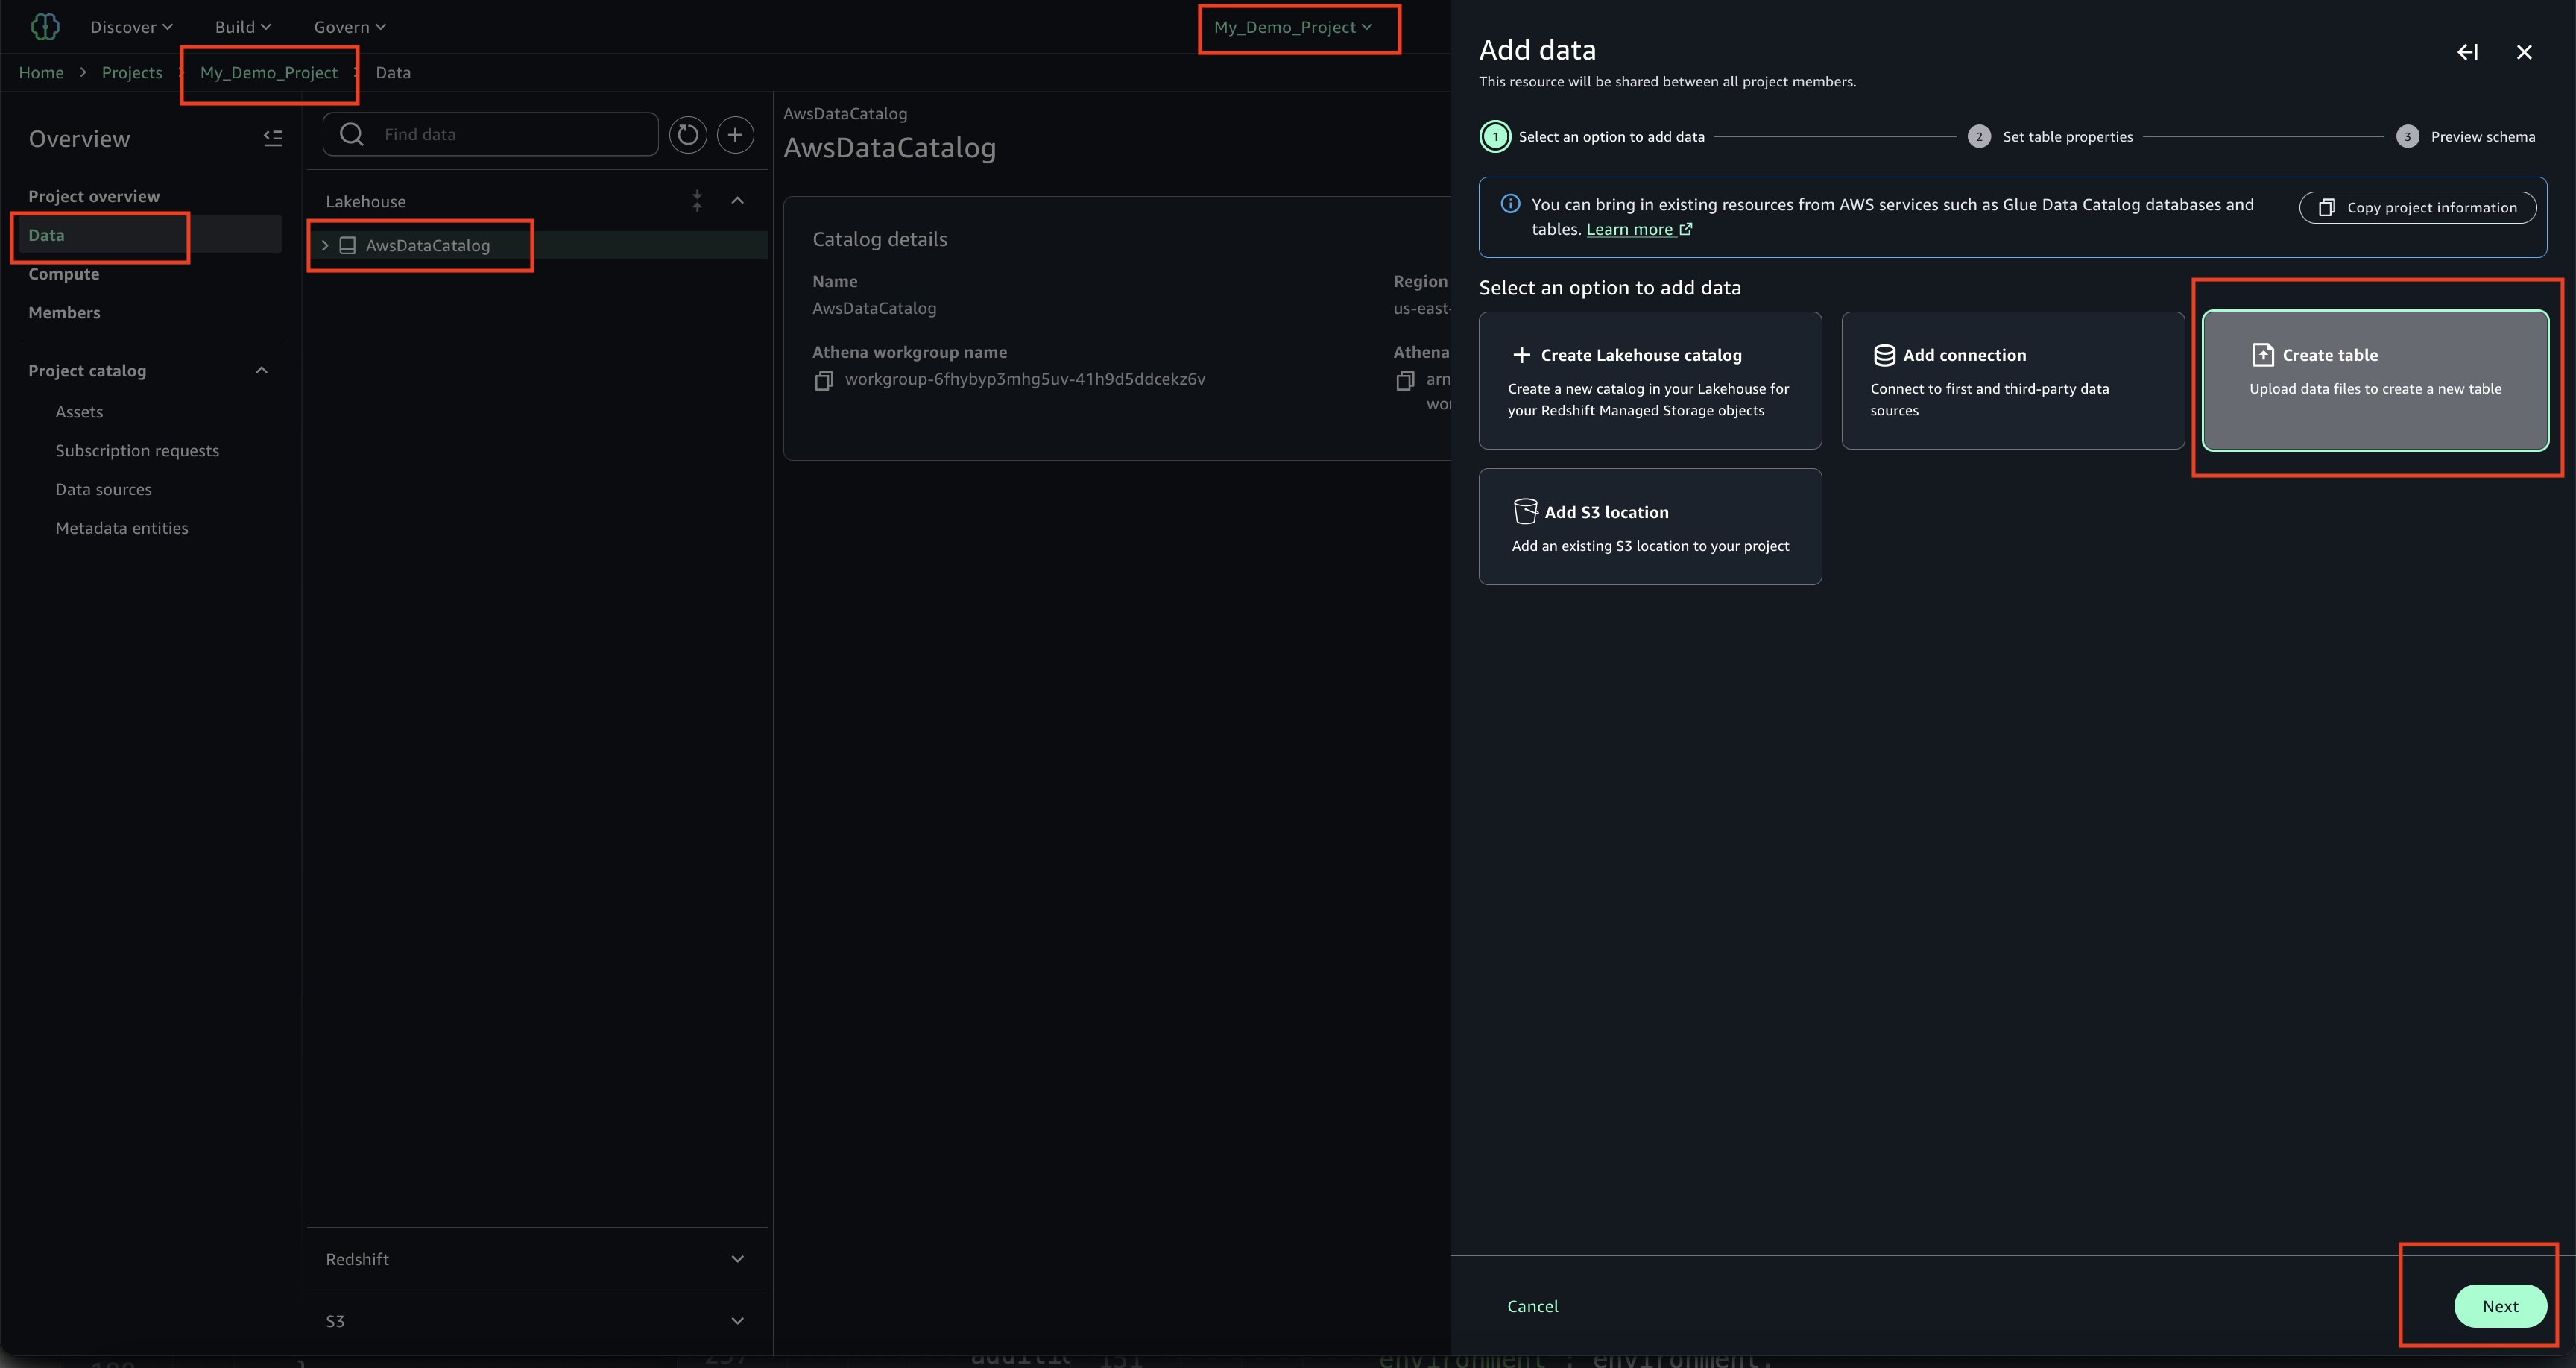
    1. In your project ‘My_Demo_Project’, click on Data. Choose the plus sign to add a data set.

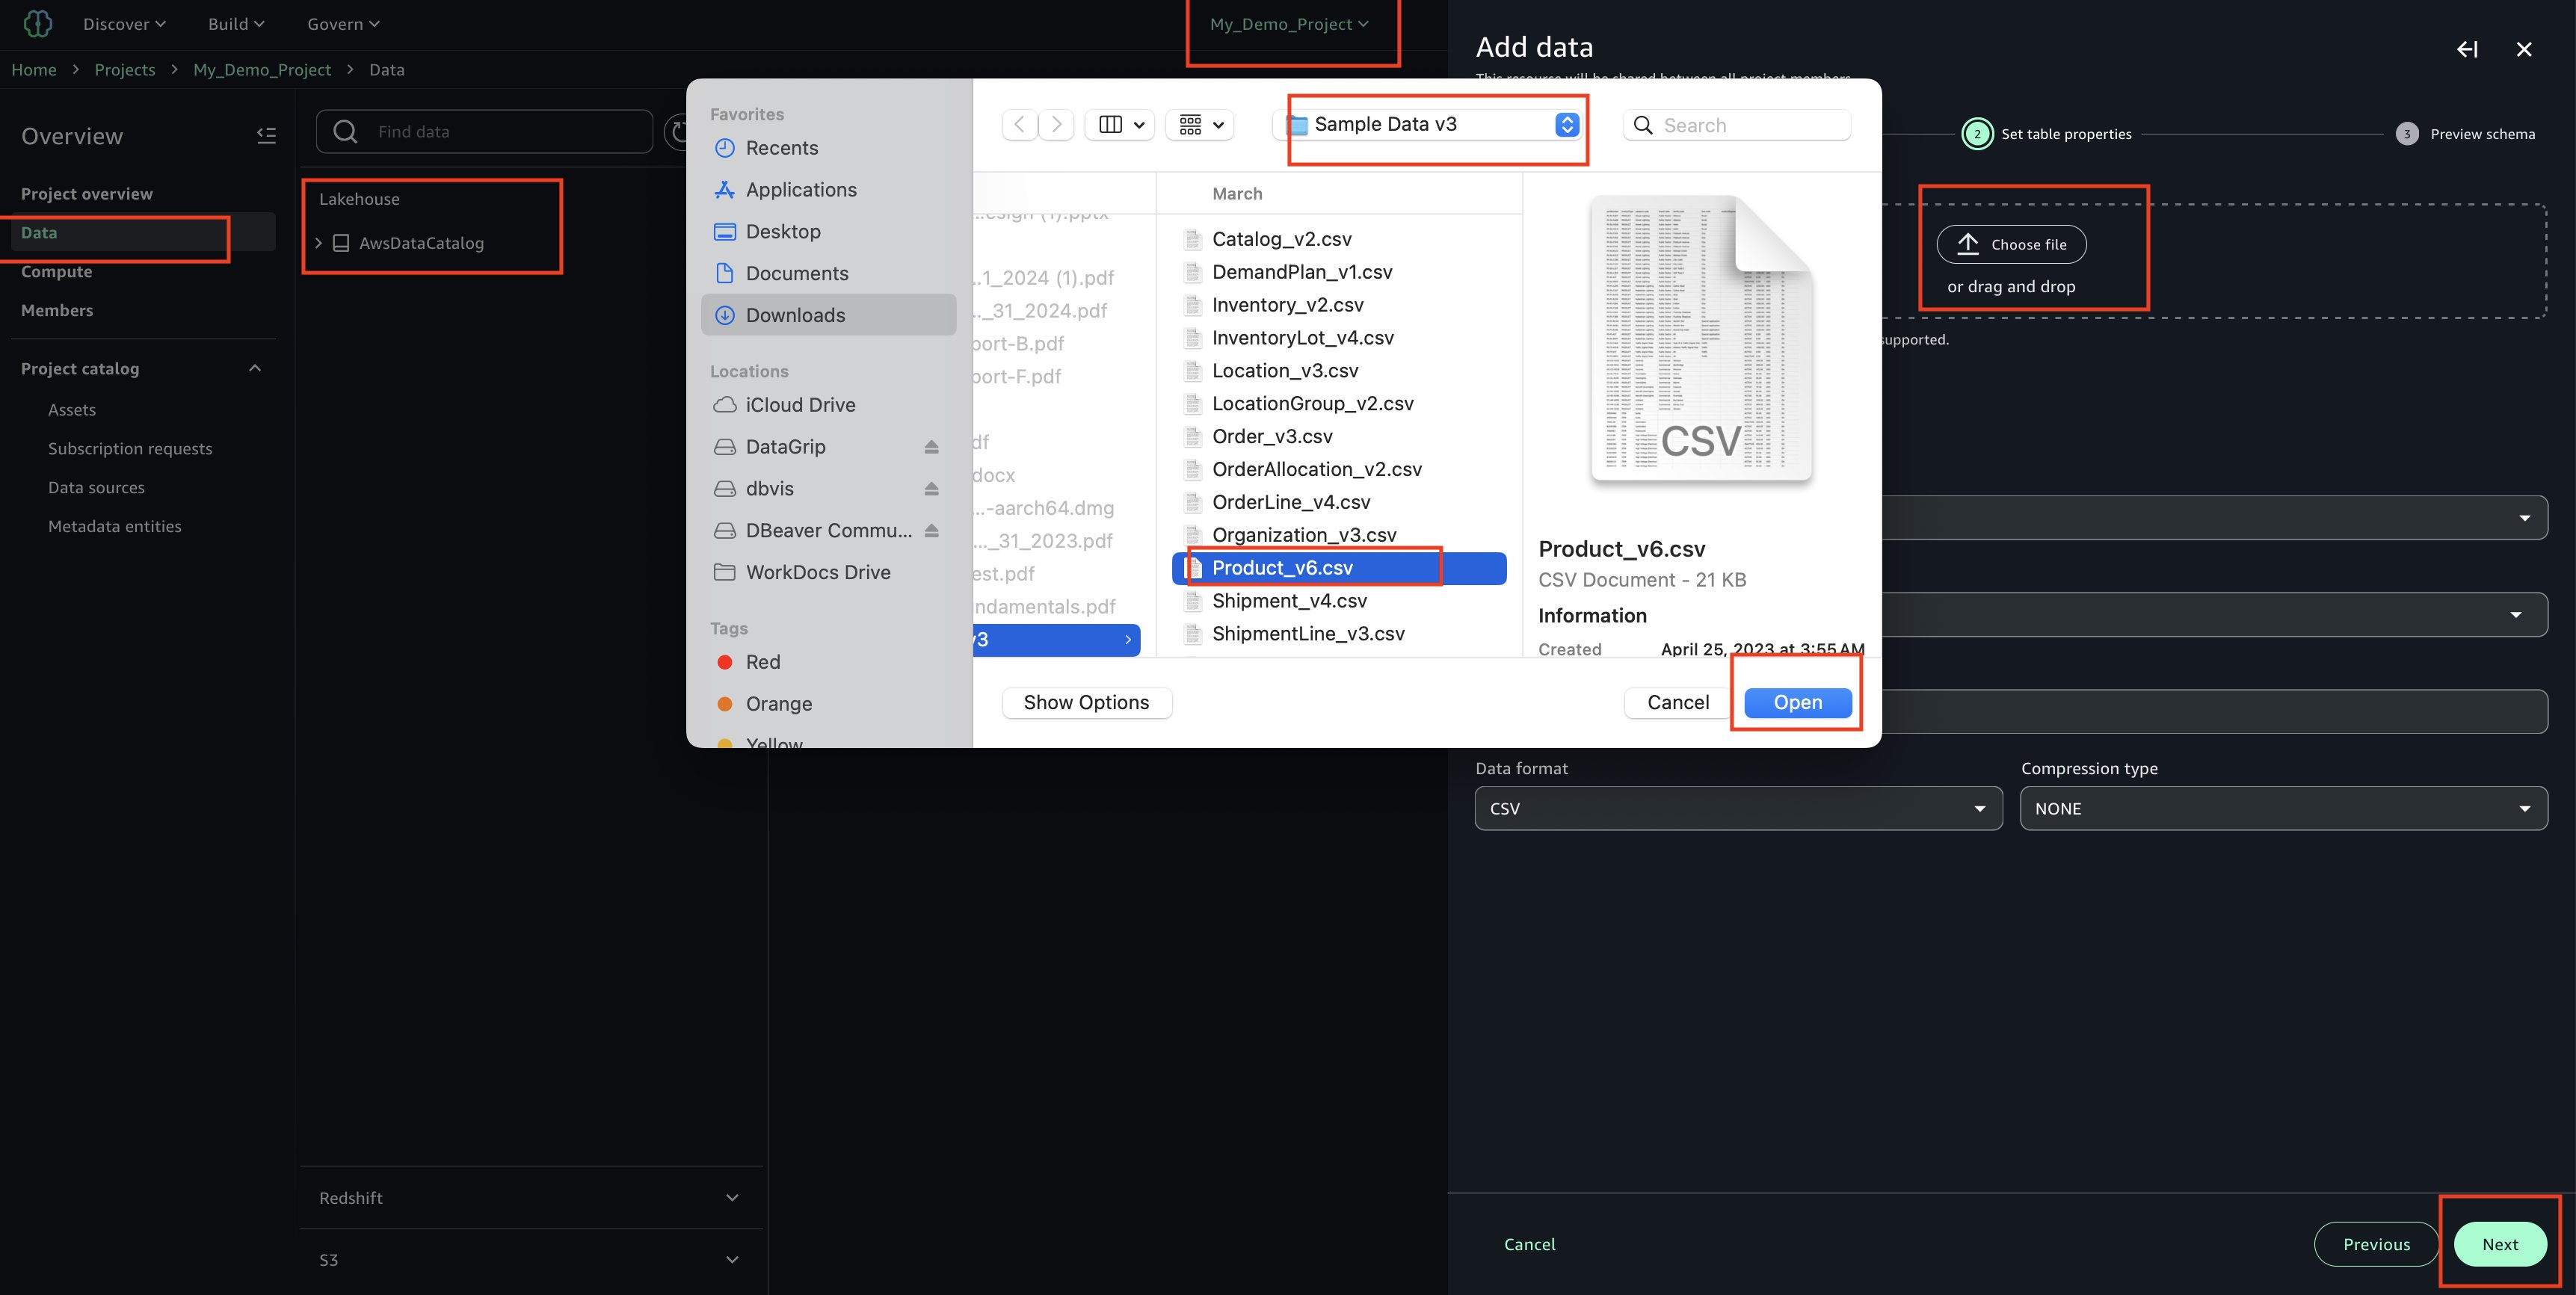
    2. Upload your CSV file using the sample ‘Product_v6.csv’ found in the checkout folder of the ‘sample-sagemaker-unified-studio-governance-notifications’ GitHub repository.

    3. Use table type as S3/external table.

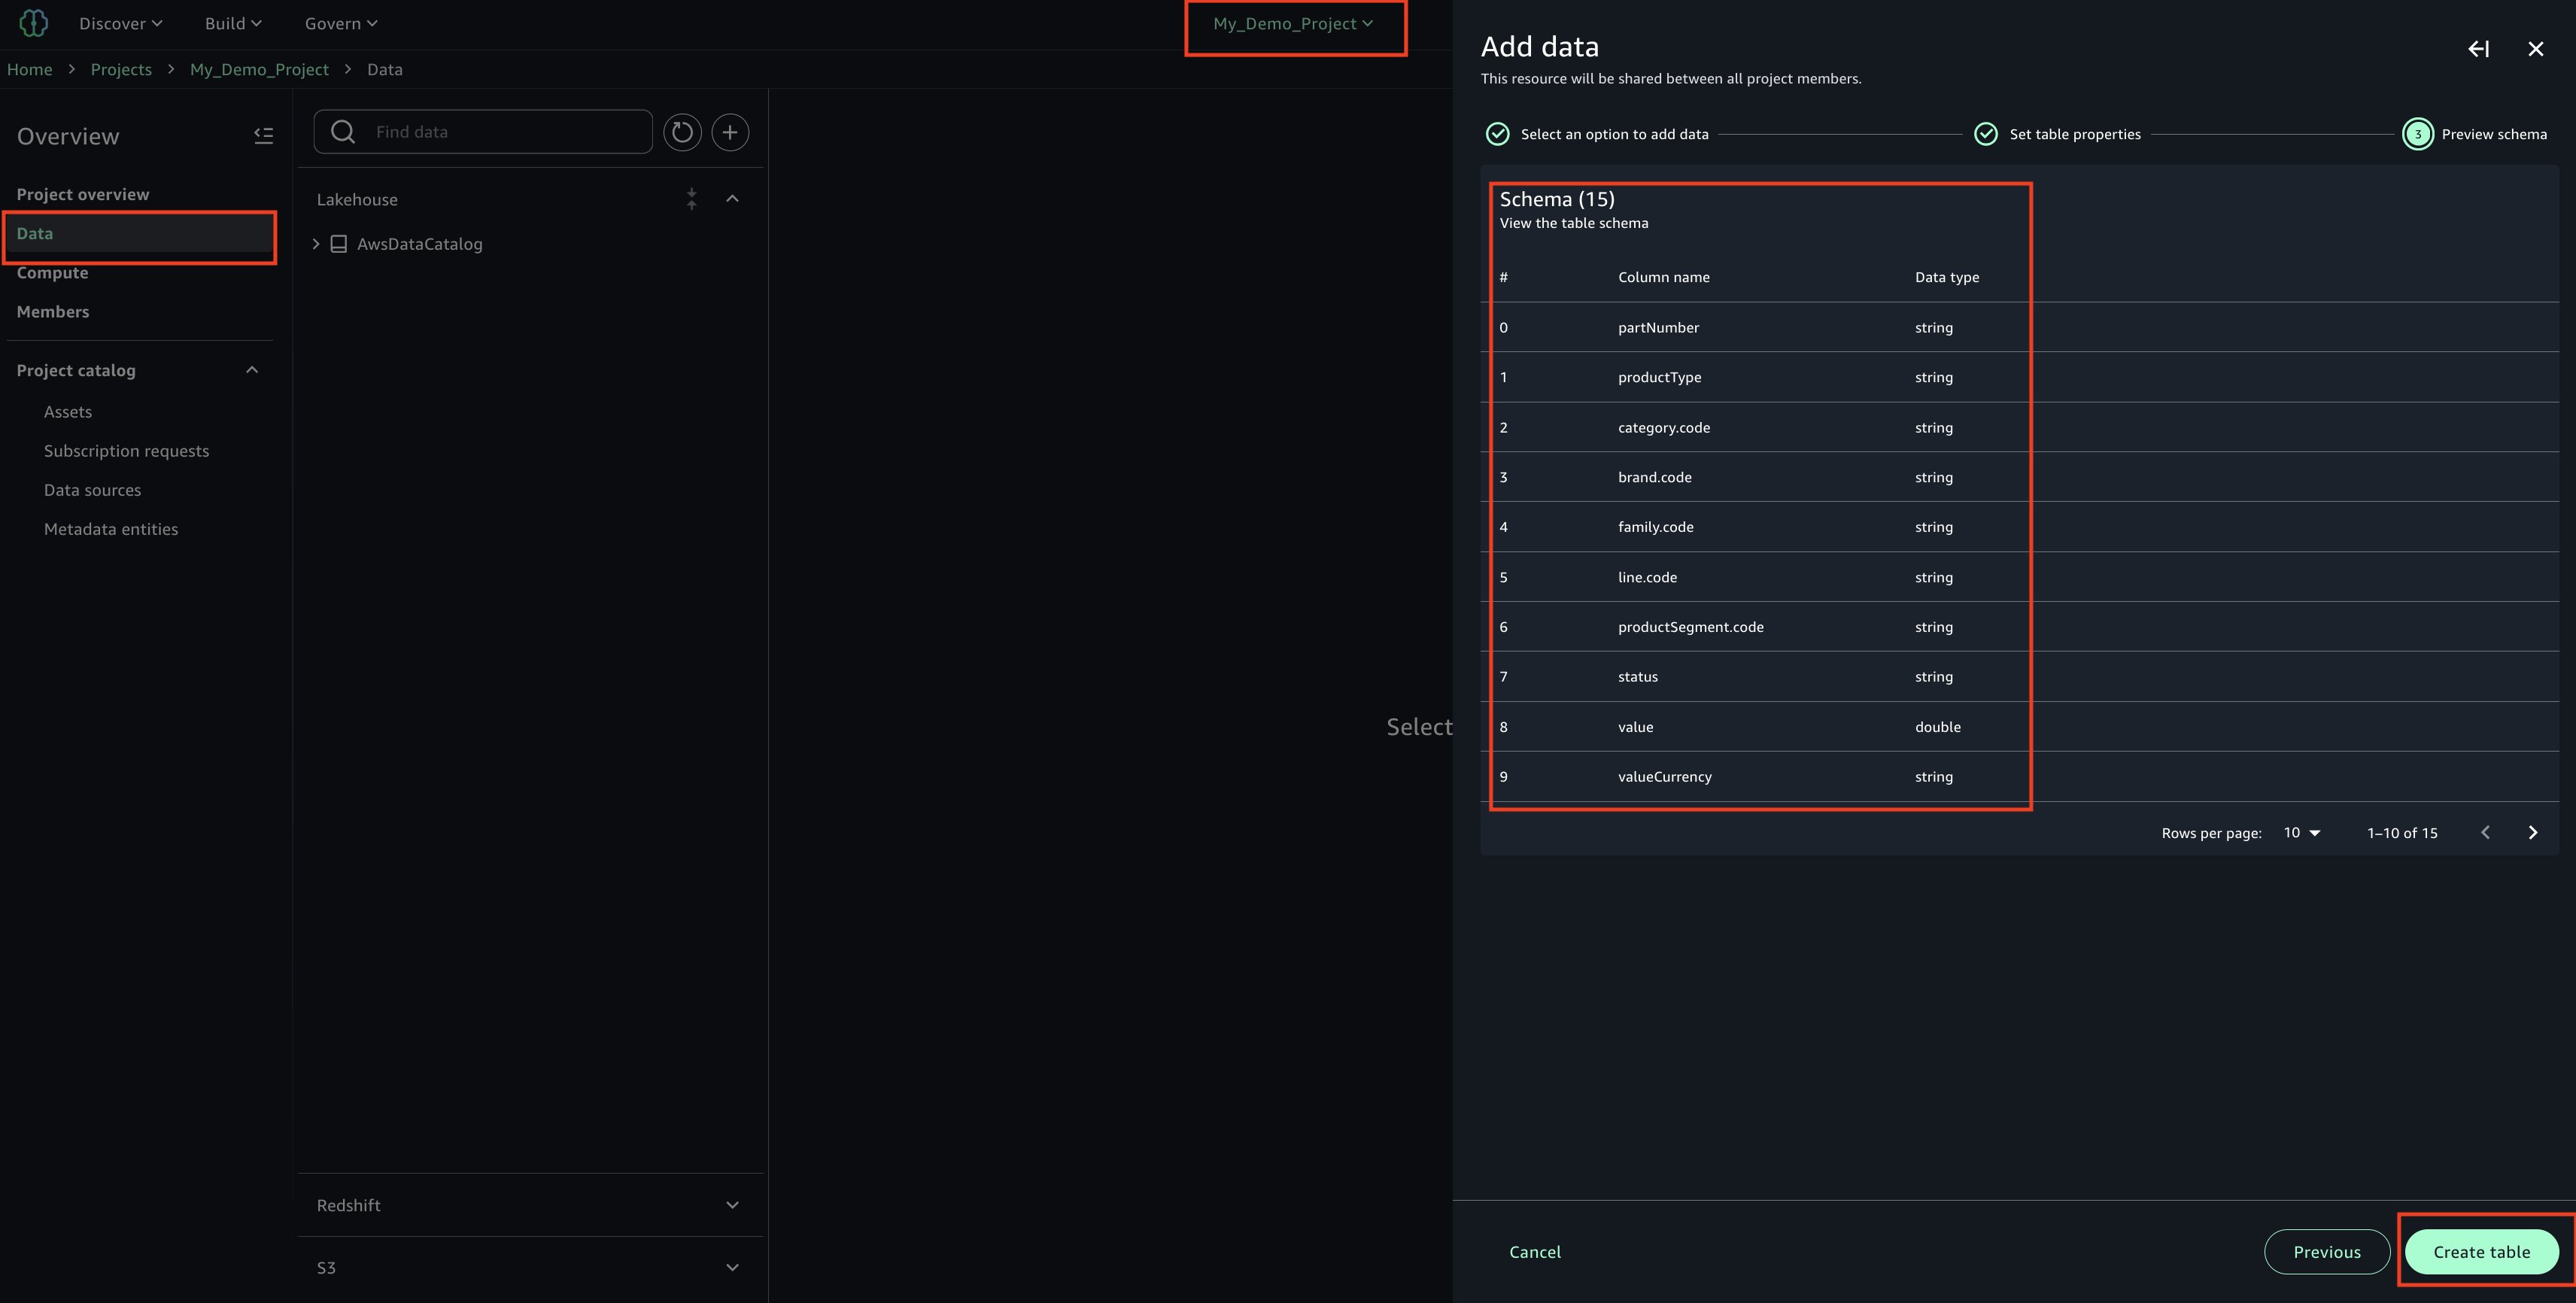
    4. Review and confirm that the column/attribute names in the uploaded CSV file.

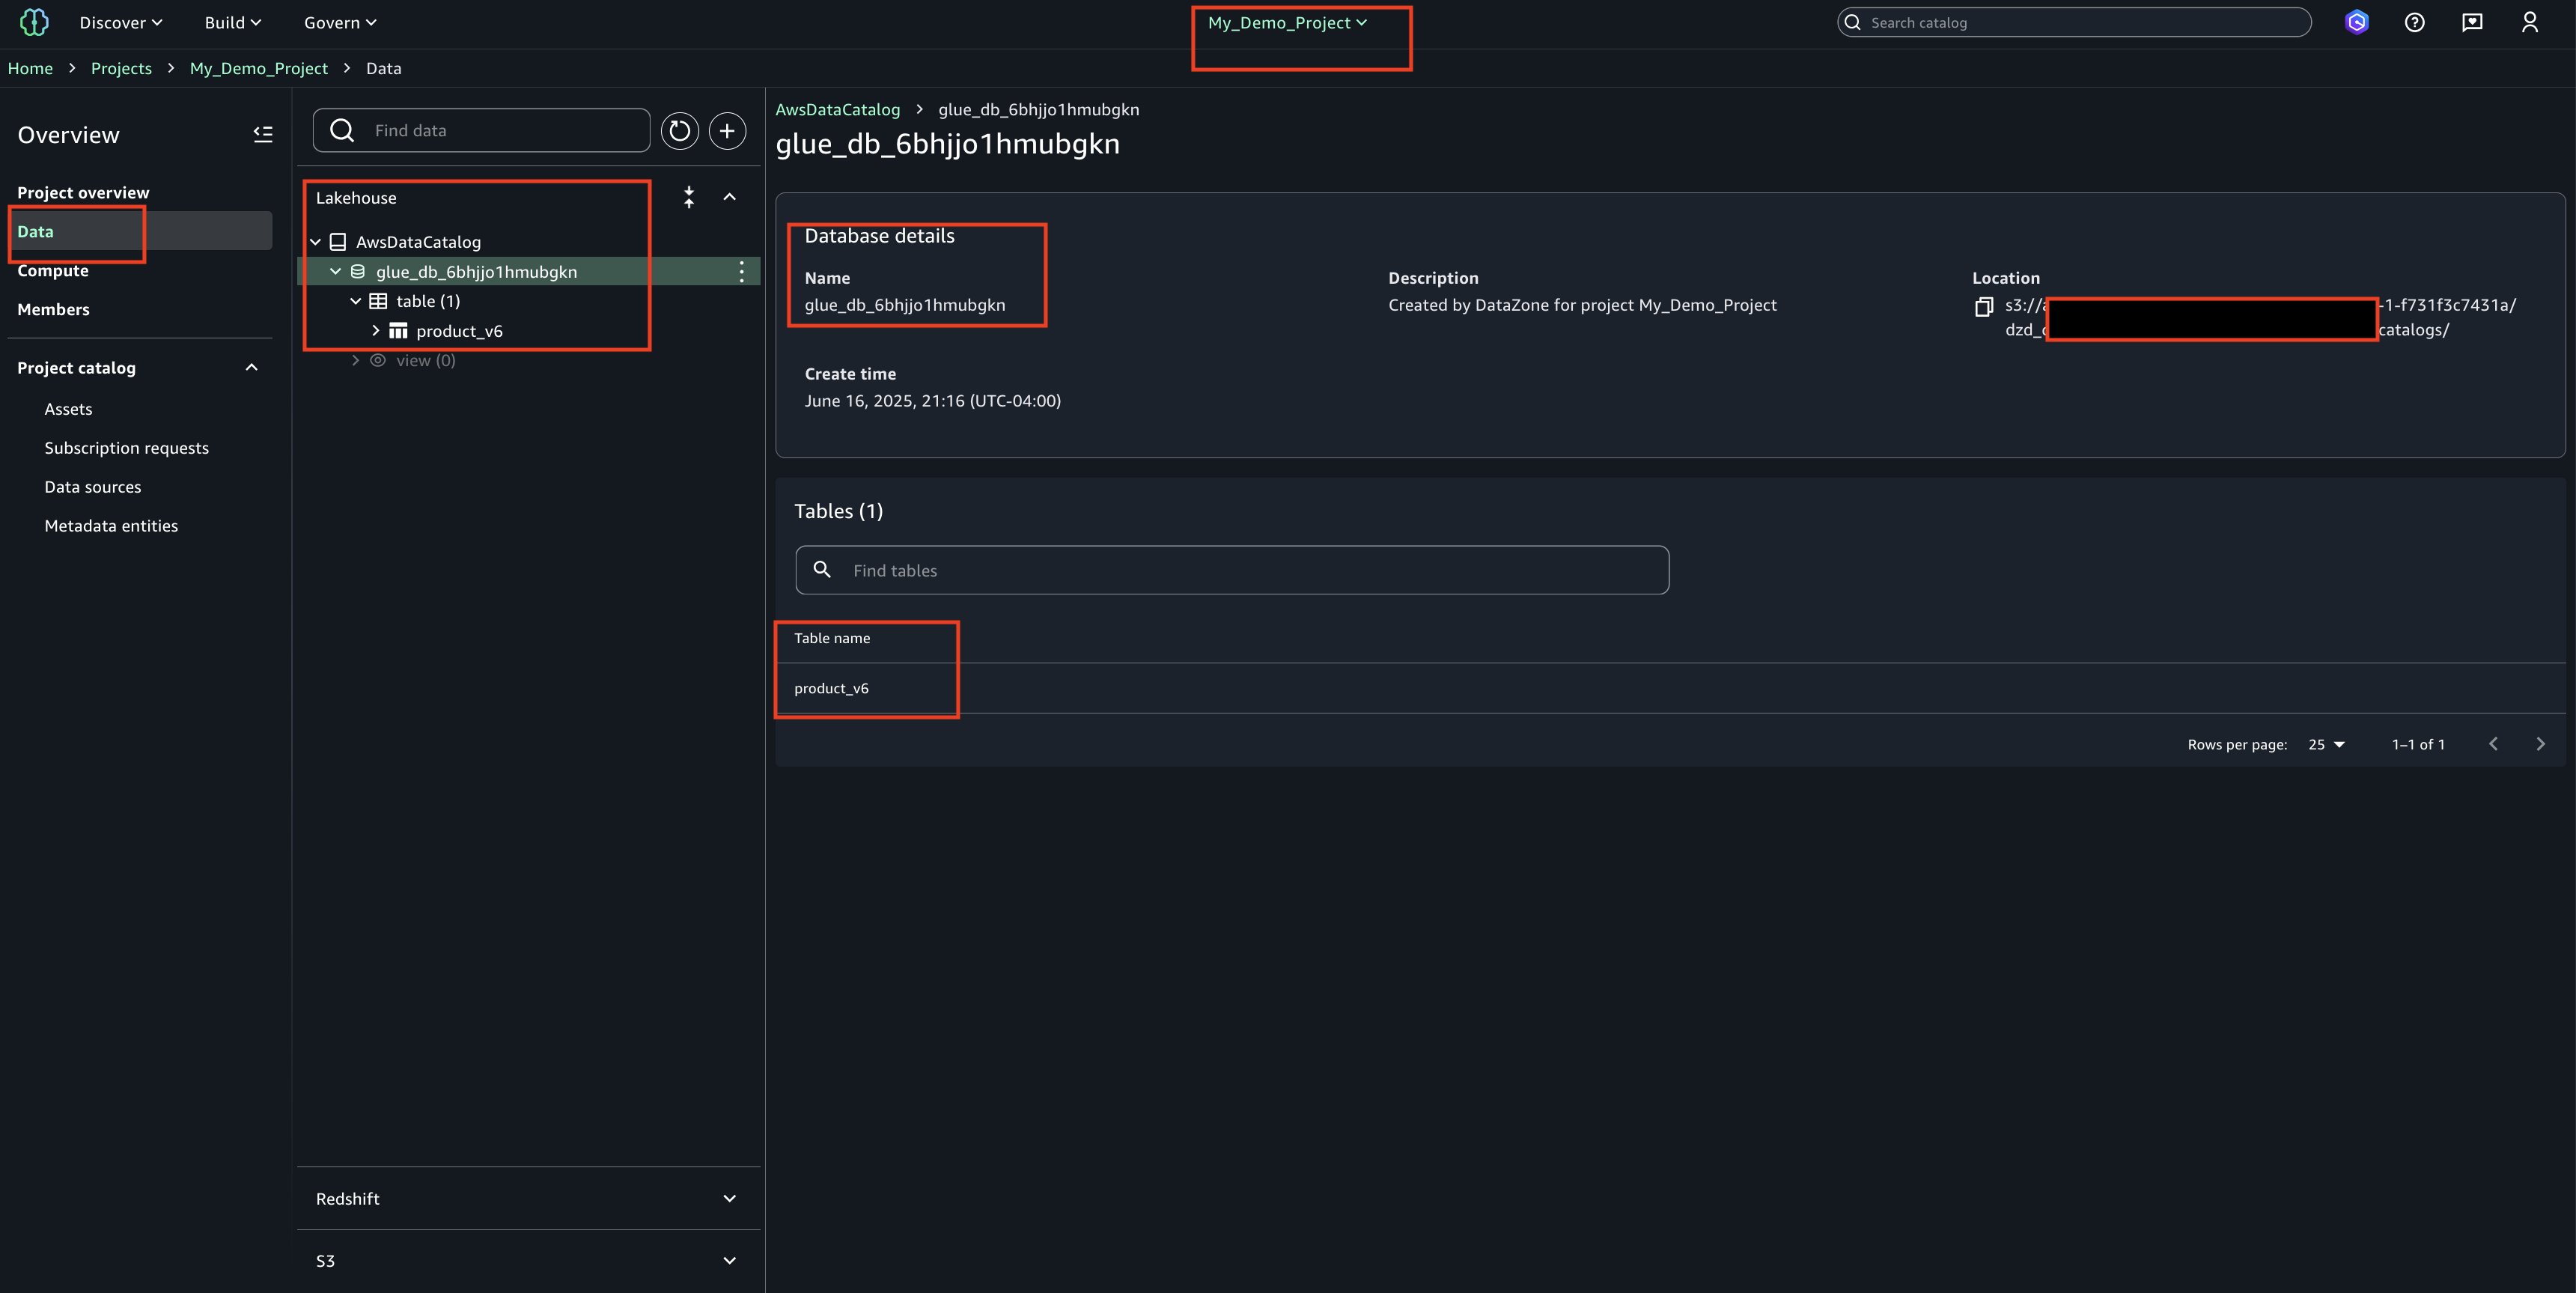
    5. Check the Glue database(glue_db_<unique_id>) to confirm that the table has been created and properly imported
  3. Publish Asset
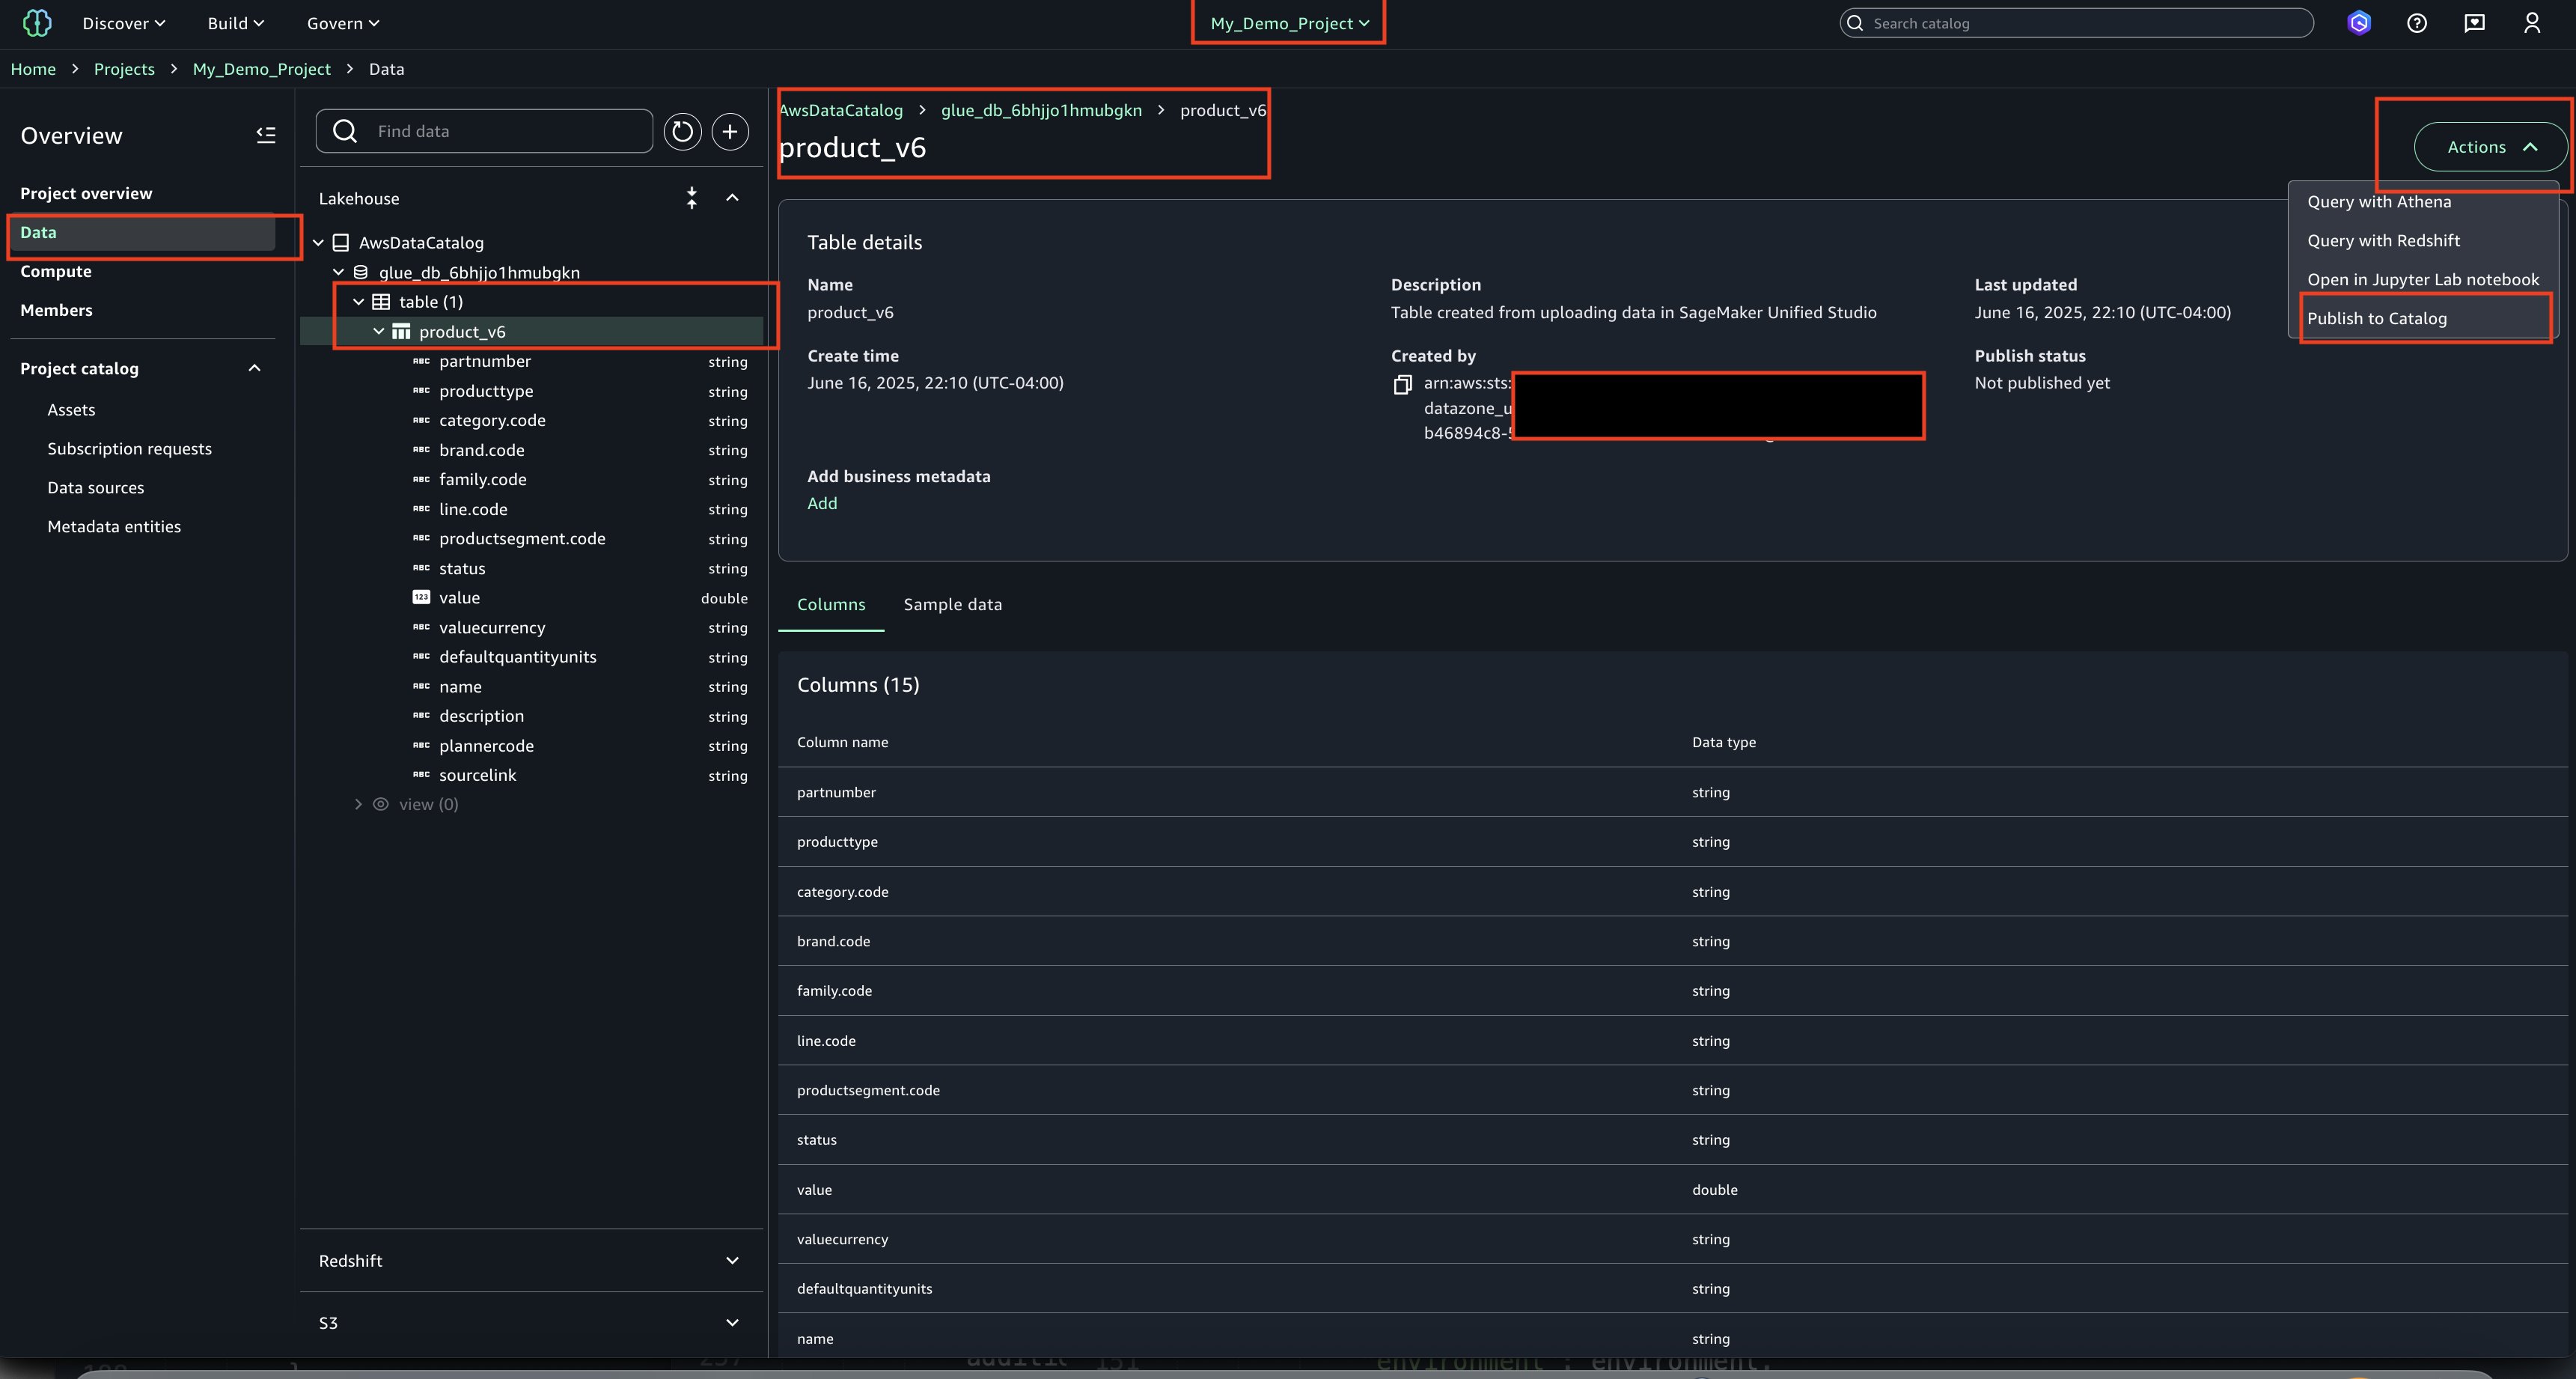
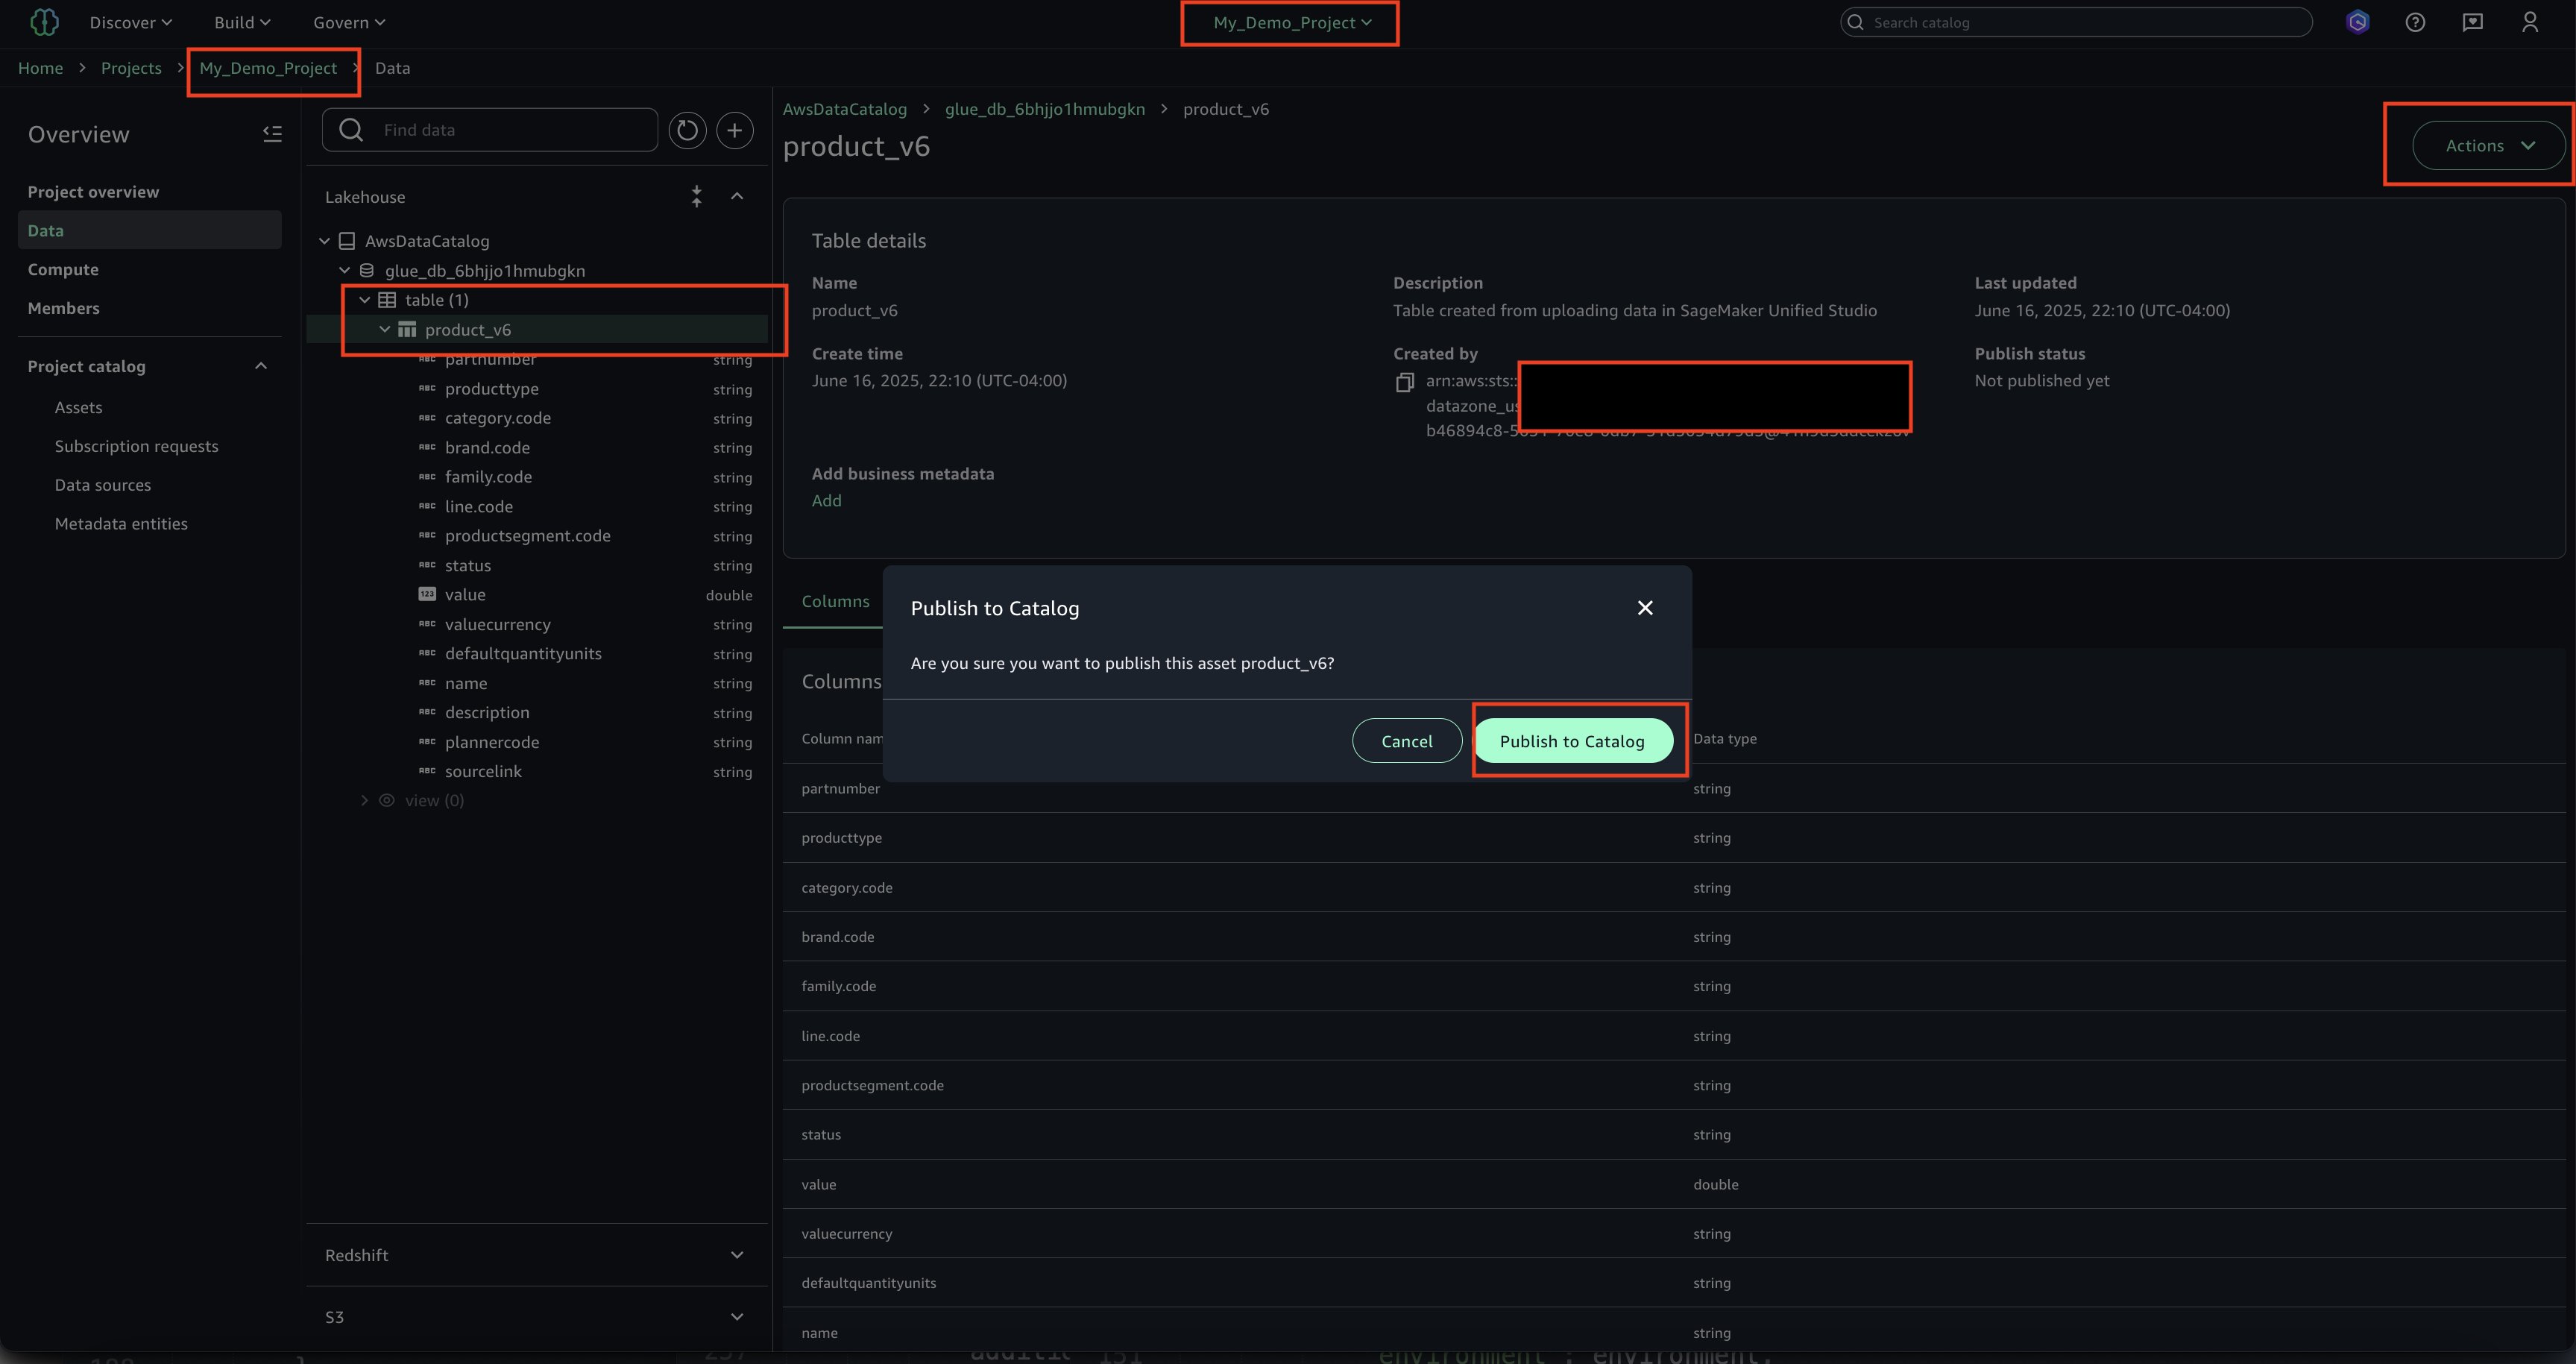
    1. Select the asset, choose Actions and Publish to Catalog.

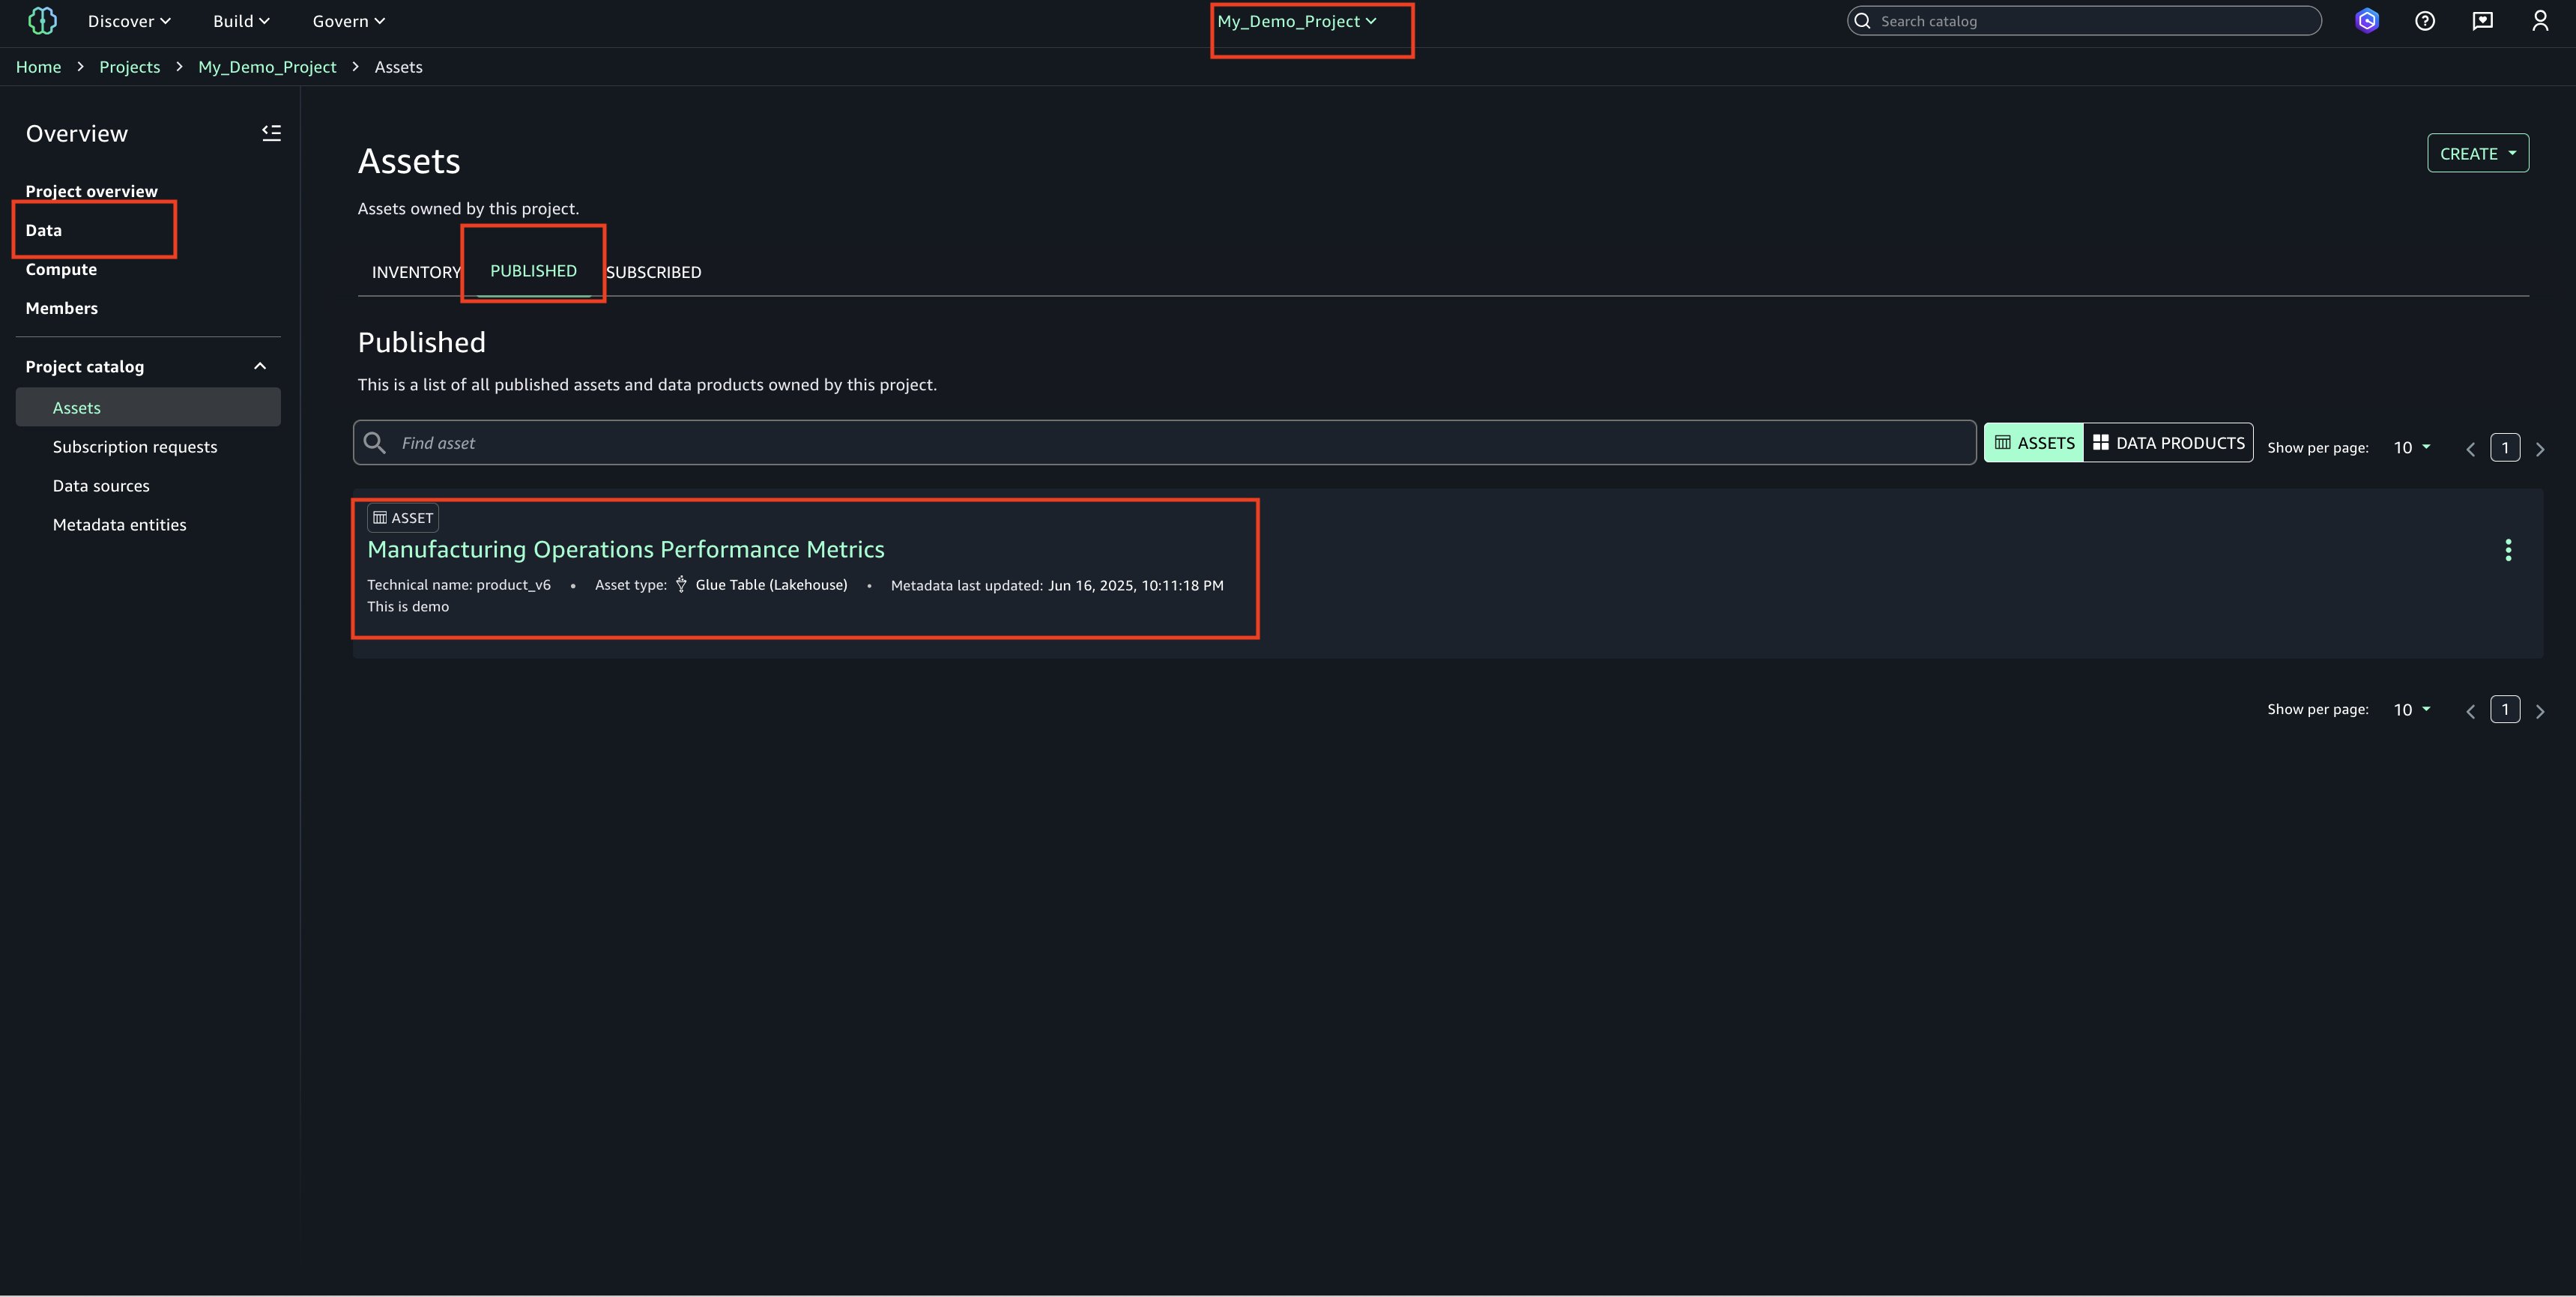
    2. View the published asset below.

    3. In the Project Catalog’s Assets section, locate the highlighted entry and verify the published table’s name

    4. Choose the asset name to display additional details and properties about the table/asset.
  4. Email Alerts
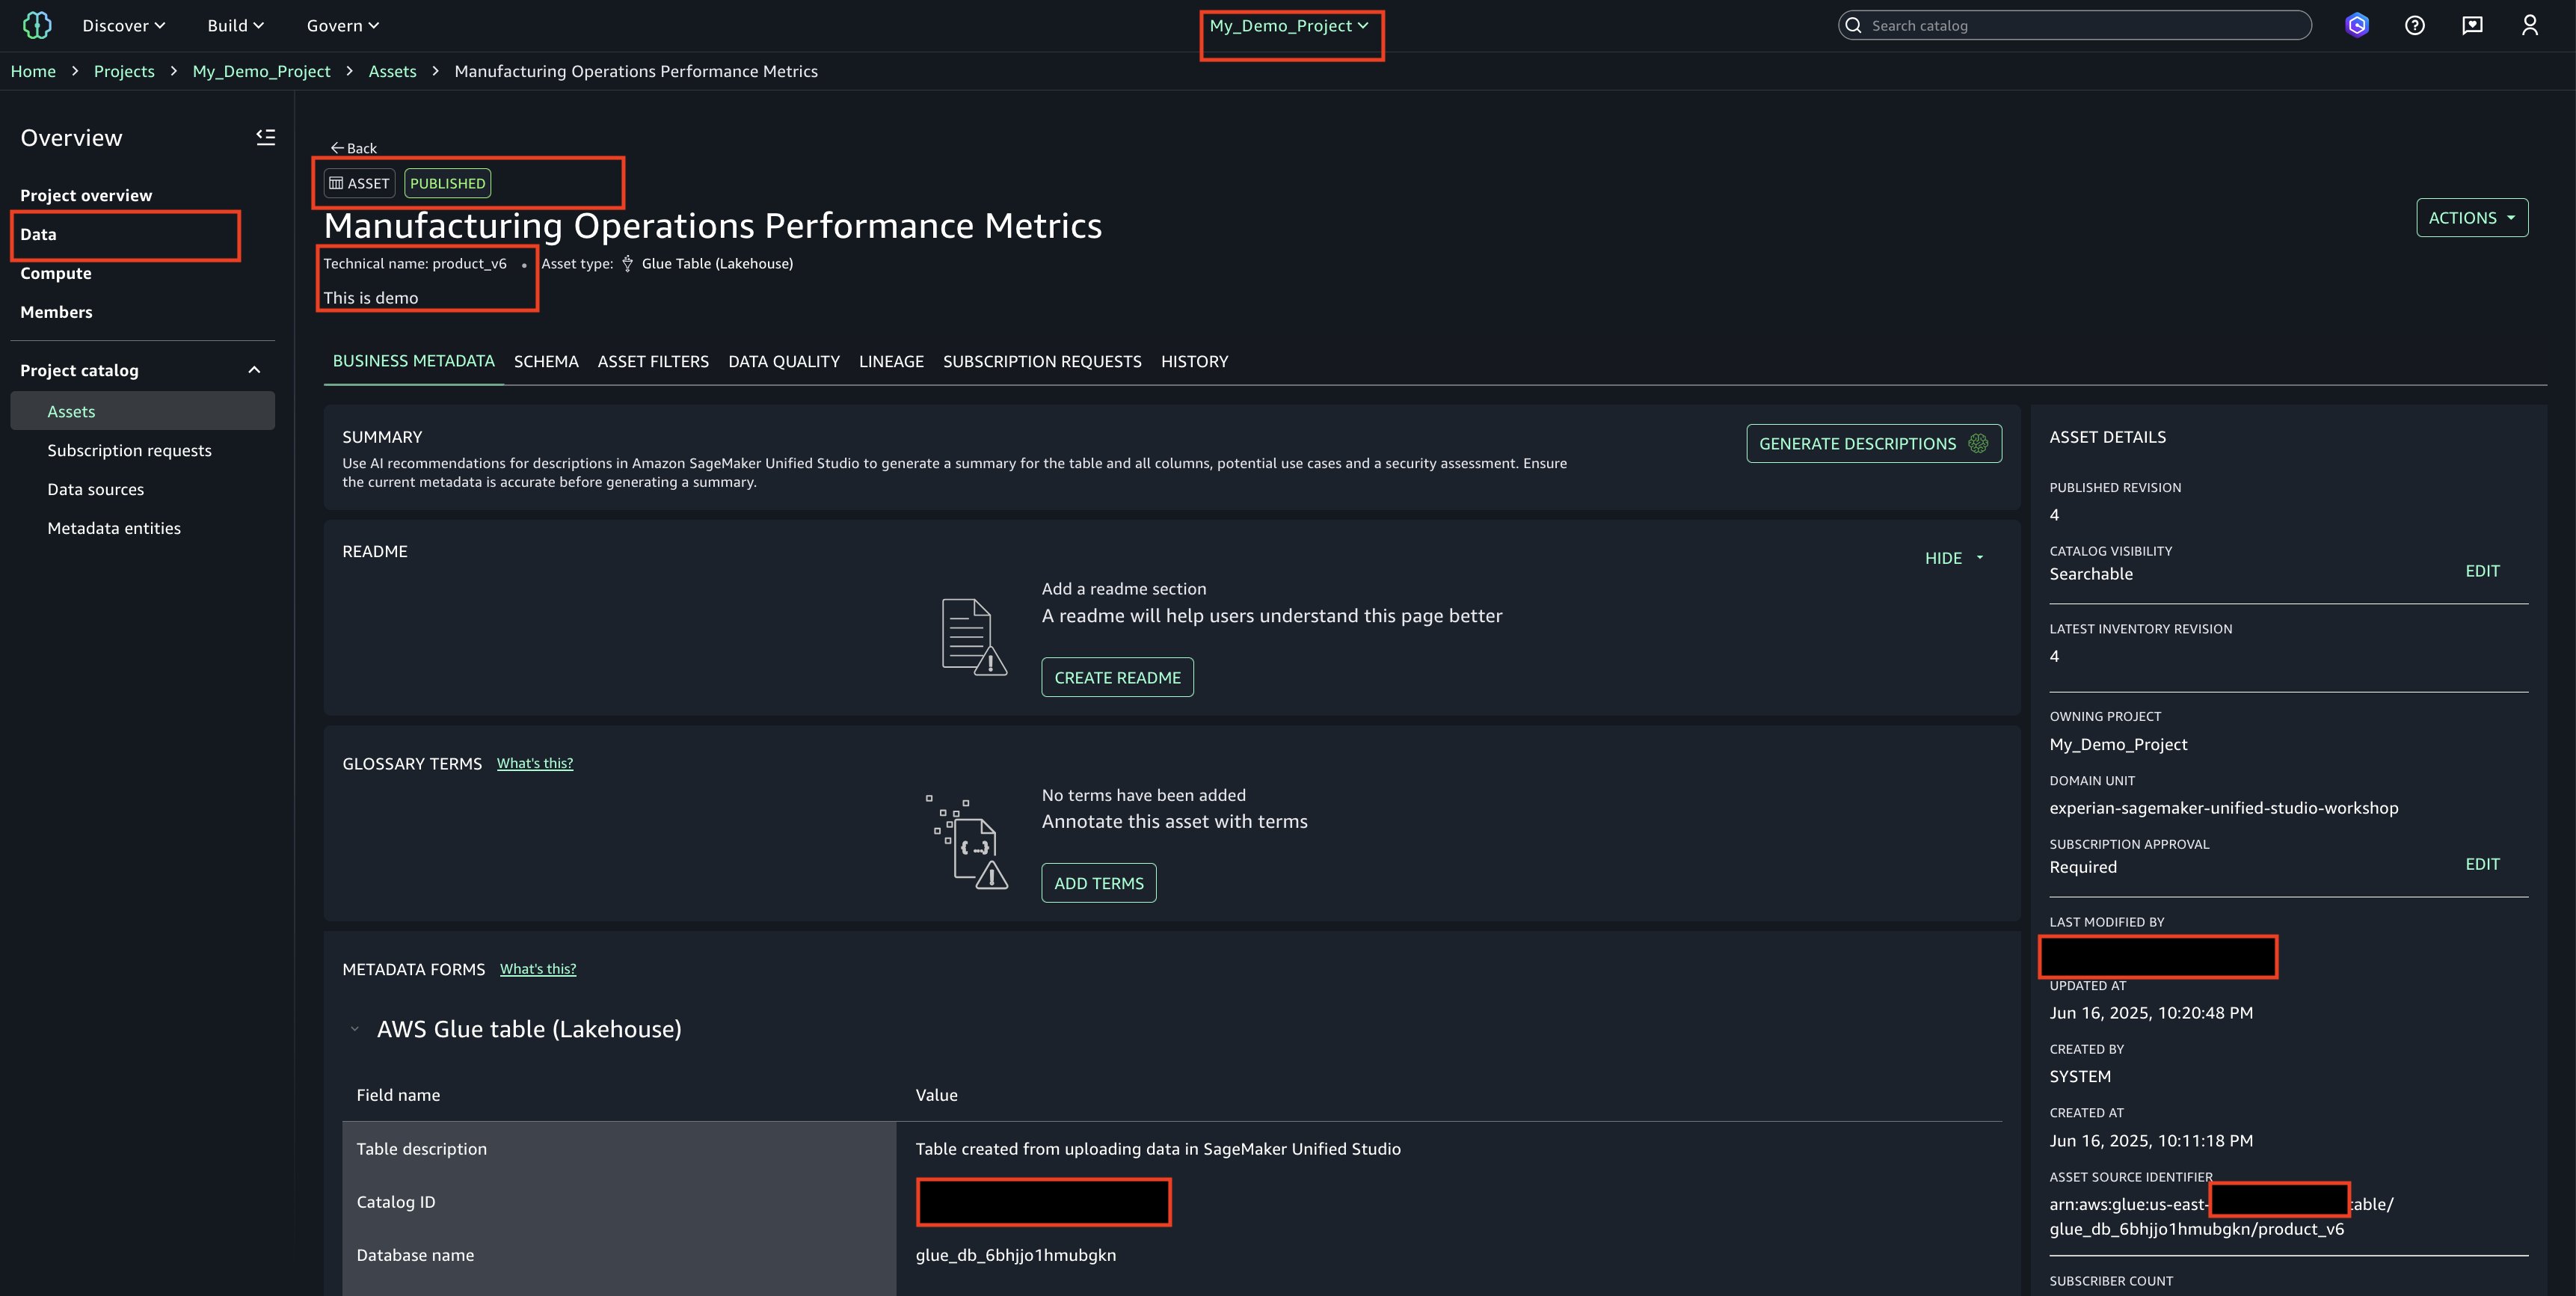
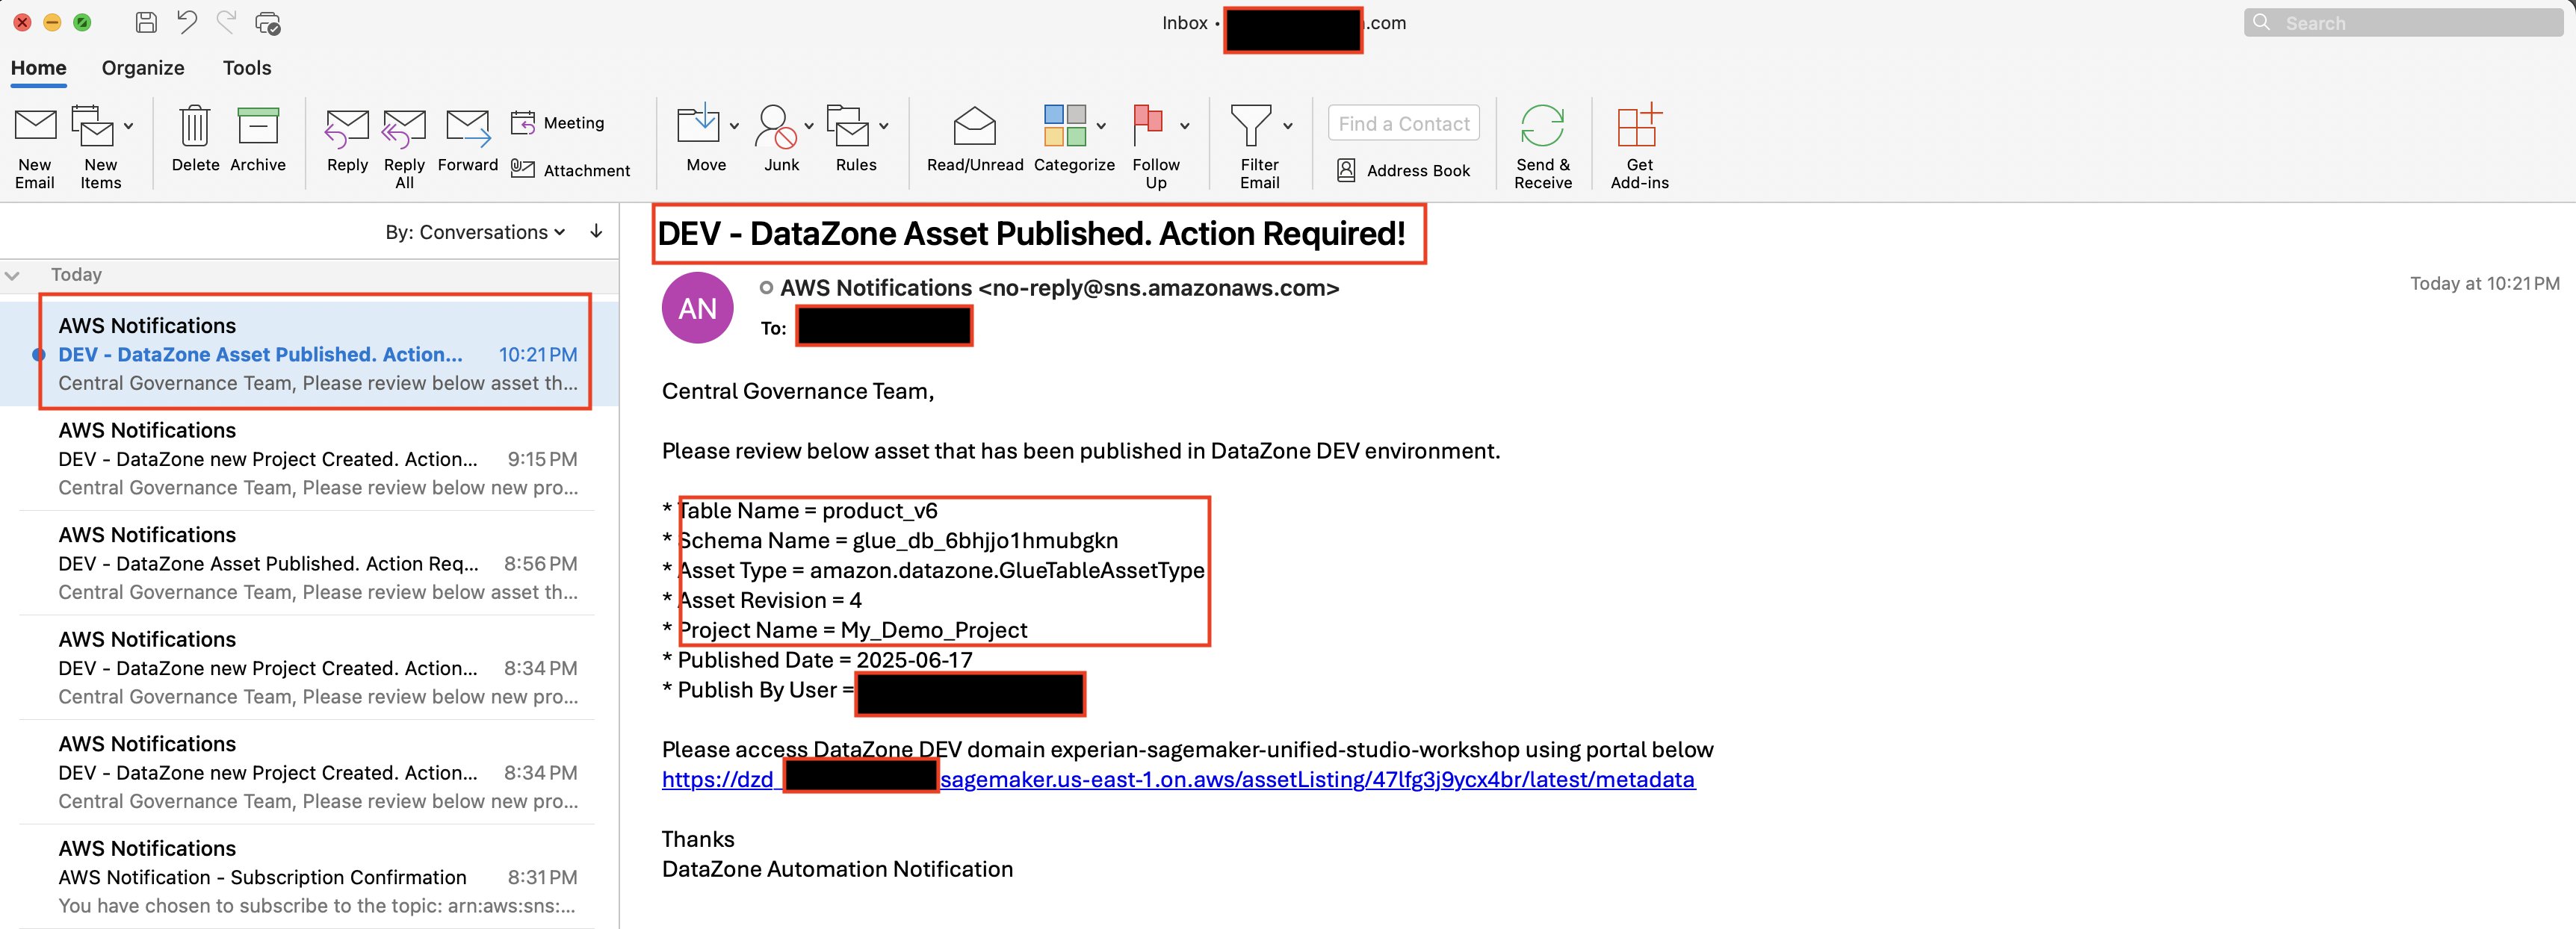
    1. Once the asset is published to SageMaker Unified studio, you’ll receive an email alert sent with details of the published asset. Central governance teams can use this alert to review the published asset to ensure it aligns with the enterprise standards.

      Email alerts are sent to notify users when assets have been published

Cleanup

To clean up your resources, complete the following steps:

cdk destroy --profile <PIPELINE-PROFILE>

Conclusion

In this post, you learned how to build an automated notification system for Amazon SageMaker Unified Studio using AWS services. Specifically, we covered:

  • How to set up event-driven notifications from Amazon SageMaker Unified Studio leveraging Amazon EventBridge, AWS Lambda, and Amazon SNS
  • The step-by-step process of deploying the solution using AWS CDK
  • Practical examples of monitoring critical events like project creation and asset publishing
  • How to integrate AWS Lambda permissions with SageMaker Unified Studio for secure operations
  • Best practices for implementing governance controls through automated notifications

Amazon SageMaker Catalog helps governance teams stay informed of catalog activities in real-time, enabling them to maintain organizational standards as their Data and ML platforms scale. The architecture is flexible and can be extended to integrate with enterprise workflow tools like ServiceNow or to monitor additional event types based on your organization’s needs.

We look forward to hearing how you adapt this solution for your organization’s governance needs. Fork the CDK code from our repository and share your implementation experience in the comments below


About the Authors

Himanshu Sahni

Himanshu Sahni

Himanshu is a Senior Data and AI Architect in AWS Professional Services. Himanshu specializes in building Data and Analytics solutions for enterprise customers using AWS tools and services. He is an expert in AI/ ML and Big Data tools like Spark, AWS Glue and Amazon EMR. Outside of work, Himanshu likes playing chess and tennis.

Rajiv Upadhyay

Rajiv Upadhyay

Rajiv is a Data Architect at AWS, specialized in building Data and Analytics solutions for enterprise customers using AWS tools and services. He guides organizations through their digital transformation journey, with expertise in data lakes, data governance, and AI/ML solutions.

Jitesh Kumar

Jitesh Kumar

Jitesh is a Senior Customer Solutions Manager at Amazon Web Services (AWS), where he helps organizations realize the full potential of cloud technologies. Passionate about driving digital innovation, Jitesh combines deep technical knowledge with a customer-first mindset to guide enterprises through their cloud transformation journeys and deliver measurable business outcomes.

Track OTP success with AWS End User Messaging SMS feedback

Post Syndicated from Rommel Sunga original https://aws.amazon.com/blogs/messaging-and-targeting/track-otp-success-with-aws-end-user-messaging-sms-feedback/

In this post, we show how to implement message feedback for SMS one-time passwords (OTPs) using AWS End User Messaging. OTP verification through SMS is a fundamental component of modern authentication systems. Although sending OTPs follows an established pattern, tracking their delivery and usage presents several challenges. This post shows how to implement the AWS End User Messaging Message Feedback API to monitor OTP delivery and conversion rates effectively. This post highlights the Message Feedback API in an OTP use case; for practical examples and detailed guidance on building a secure OTP architecture, see Build a Secure One-Time Password Architecture with AWS.

Challenges with OTP tracking

Organizations commonly face these key challenges with OTP tracking:

  • Relying solely on Delivery Receipt (DLR) data for confirming message delivery, which is third-party carrier data that can be subject to interpretation by carriers or message providers, whereas conversion tracking through message feedback provides first-party data that can more accurately reflect actual message delivery and usage
  • Measuring accurate user authentication success rates
  • Identifying OTP verification issues across different geographic regions, carriers and delivery paths

To address these challenges, you can use the AWS End User Messaging Message Feedback API to track delivery and conversion rates, providing first-party data for more accurate insights into message delivery and usage patterns. Although OTP use cases are the most common and serve as our example implementation of message feedback, the same tracking logic can also be applied to other types of SMS conversions, such as promotional link clicks, shopping cart additions, account activations, appointment confirmations, and delivery notifications.

Solution overview

The OTP message flow consists of two main phases. Let’s first examine how the system handles the initial OTP request.

Phase 1: OTP request flow

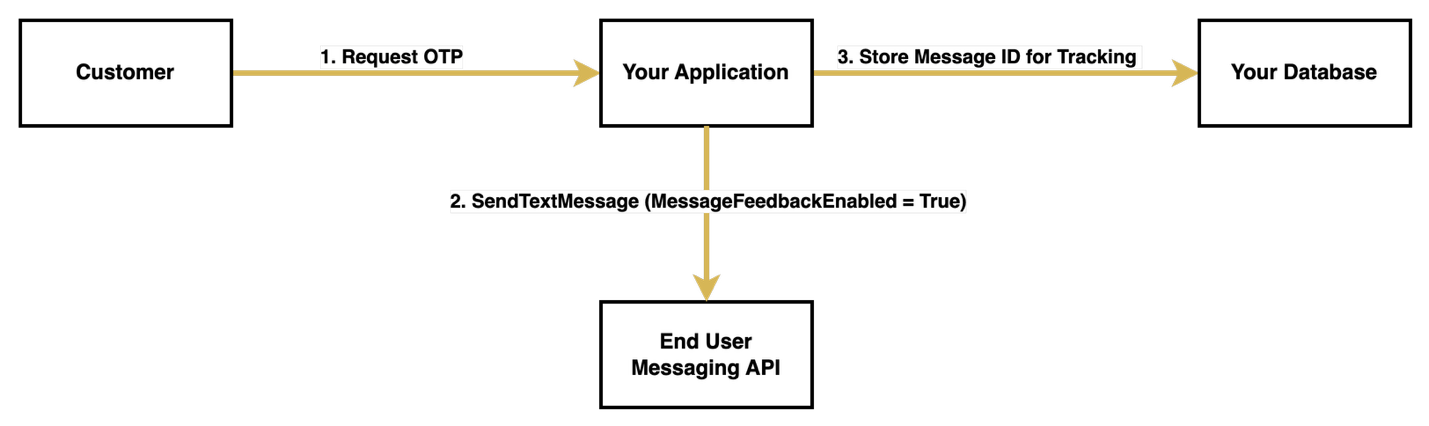
When a customer initiates an OTP request, your system begins a carefully orchestrated process. First, your application receives this request and generates a unique OTP. With the OTP generated, your system prepares to send it through the AWS End User Messaging API, specifically enabling message feedback tracking by setting the MessageFeedbackEnabled parameter to true when calling SendTextMessage.

Upon successful sending, it returns a unique message ID, which your system must store alongside the generated OTP. This message ID serves as a crucial tracking identifier for the entire verification process. The message is then dispatched to the customer’s device, and your system enters a waiting state, ready to process the verification attempt.

The following diagram illustrates the OTP request flow.

OTP Request Flow Diagram

Phase 2: OTP verification flow

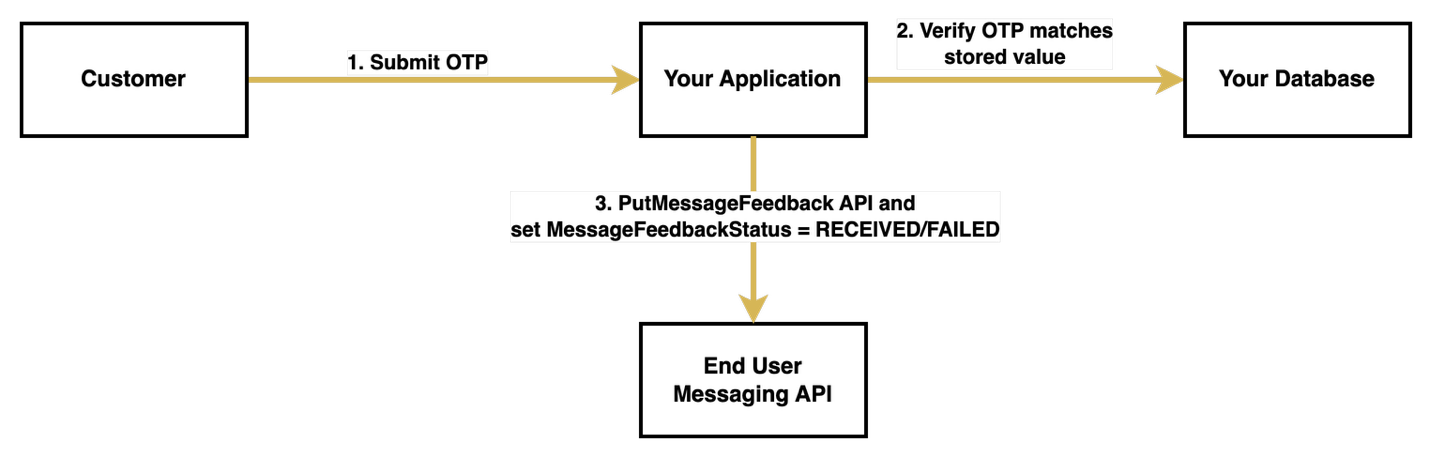
The verification process begins when the customer receives the OTP through SMS and submits it back to your system. Upon receiving the submission, your system first validates the OTP against the stored value. This verification step is critical, because its outcome determines how you will update the message feedback status.

If the customer successfully verifies the OTP, your system calls the PutMessageFeedback API with the stored message ID and sets the status to "RECEIVED", indicating successful delivery and usage of the OTP. However, if the verification fails or the customer doesn’t respond within the timeout period, your system sets the status to "FAILED".

If your system doesn’t explicitly update the feedback status within 1 hour, AWS automatically sets it to "FAILED".

The following diagram illustrates the OTP verification flow.

Prerequisites

Before you begin implementing OTP message feedback, make sure you have the following components and permissions in place:

Send SMS with message feedback enabled

You can enable message feedback in two ways. The first method is to use the MessageFeedbackEnabled parameter when sending an SMS, the second is to send a message with a configuration set with message feedback already enabled. Using a configuration set is often more convenient for bulk implementations because you don’t need to specify message feedback settings in each API call.

To send an SMS with message feedback enabled directly, you can use the following function:

import boto3

# Initialize the End User Messaging client
client = boto3.client('pinpoint-sms-voice-v2')

def send_otp_with_feedback():
    # Generate a unique OTP
    otp = generate_otp()  
    
    # Send SMS with feedback enabled
    response = client.send_text_message(
        DestinationPhoneNumber='+15555550123',  # Replace with your destination phone number
        OriginationIdentity='+14255550120',  # Replace with your origination identity
        MessageBody=f'Your verification code is: {otp}',
        MessageFeedbackEnabled=True
    )
    
    # Store OTP details for verification
    store_otp_details(response['MessageId'], otp)
    return response['MessageId']

The function uses the following details:

  • store_otp_details() is a placeholder function where you store the OTP details in a database for later retrieval
  • generate_otp() is a placeholder function where you generate your OTPs to send using SMS

If you prefer to use a configuration set with message feedback enabled, you can use the following alternative function:

def send_otp_with_feedback_using_configuration_set():
    # Initialize the End User Messaging client
    client = boto3.client('pinpoint-sms-voice-v2')
    
    # Generate OTP
    otp = generate_otp()
    
    # Send SMS using configuration set
    response = client.send_text_message(
        DestinationPhoneNumber='+15555550123',  # Replace with your destination phone number
        OriginationIdentity='pool-201d59fffd554bdfbaf9ee8aEXAMPLE',  # Replace with your origination identity
        MessageBody=f'Your verification code is: {otp}',
        ConfigurationSetName='example-us-east-configuration-set'  # Replace with your configuration set name
    )
    
    # Store OTP details for later verification
    store_otp_details(response['MessageId'], otp)
    
    return response['MessageId']

Your configuration set must have message feedback enabled to use this option. You can enable it using the AWS Command Line Interface (AWS CLI) with the following command:

aws pinpoint-sms-voice-v2 set-default-message-feedback-enabled \
--configuration-set-name "YourConfigSetName" \
--message-feedback-enabled

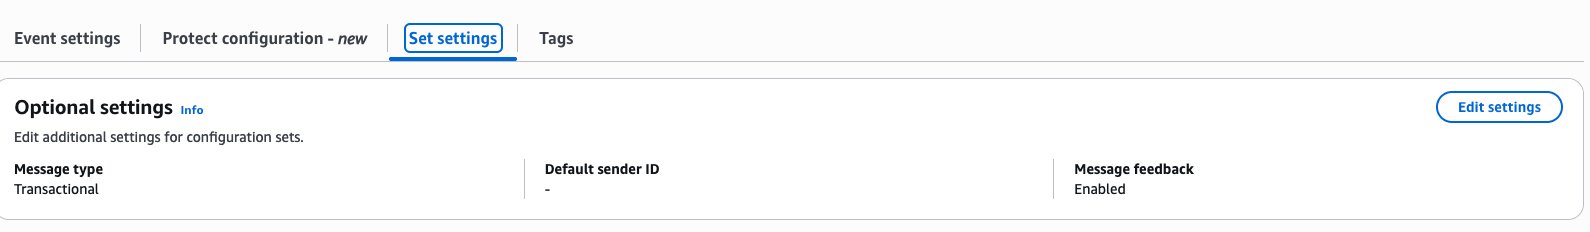
Another option is to use the AWS End User Messaging console, where you can enable message feedback under Set Settings for the desired configuration set.

Update feedback

After you send a message, you can update the message status to indicate whether a user has successfully completed an action, such as entering the OTP on your application or webpage:

def update_message_feedback(message_id: str, status: str) -> dict:
    try:
        # Initialize the End User Messaging client
        client = boto3.client('pinpoint-sms-voice-v2')
        
        # Update the message feedback status
        response = client.put_message_feedback(
            MessageId=message_id,
            MessageFeedbackStatus=status
        )
        
        return response
        
    except Exception as e:
        print(f"Error updating message feedback: {str(e)}")
        raise

# Example usage
message_id = "a1b2c3d4-5678-90ab-cdef-EXAMPLE11111"  # Replace with your message ID
status = "RECEIVED"  # Use "FAILED" for unsuccessful verifications

result = update_message_feedback(message_id, status)
print(f"Feedback status updated: {result}")

Verify feedback metrics

The AWS End User Messaging dashboard provides comprehensive metrics to help you monitor your OTP performance. The following metrics are available for customizable time periods:

  • Number of messages with feedback completion
  • Percentage of messages with feedback completion
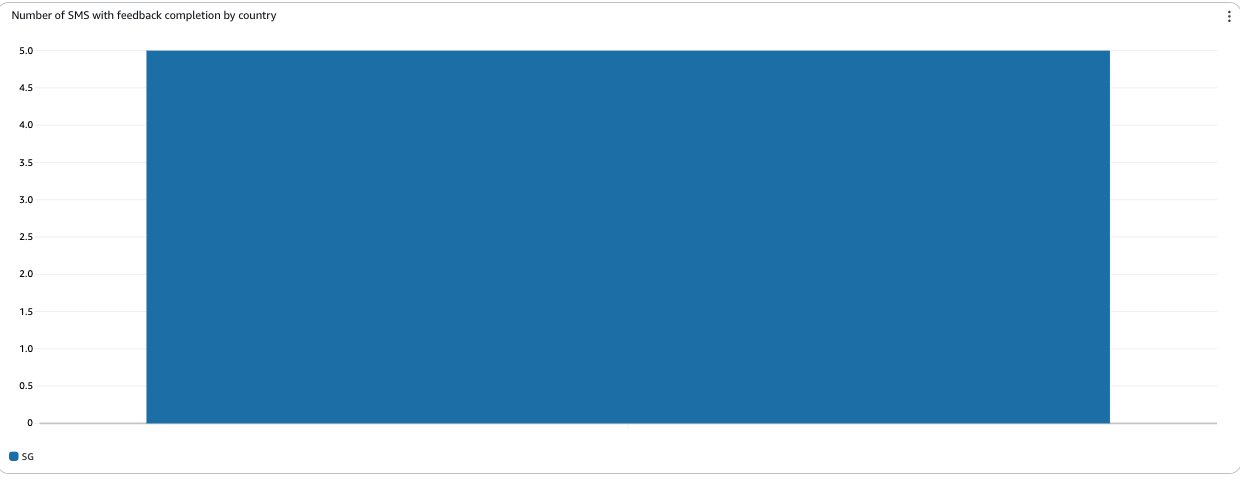
  • Number of SMS with feedback completion by country

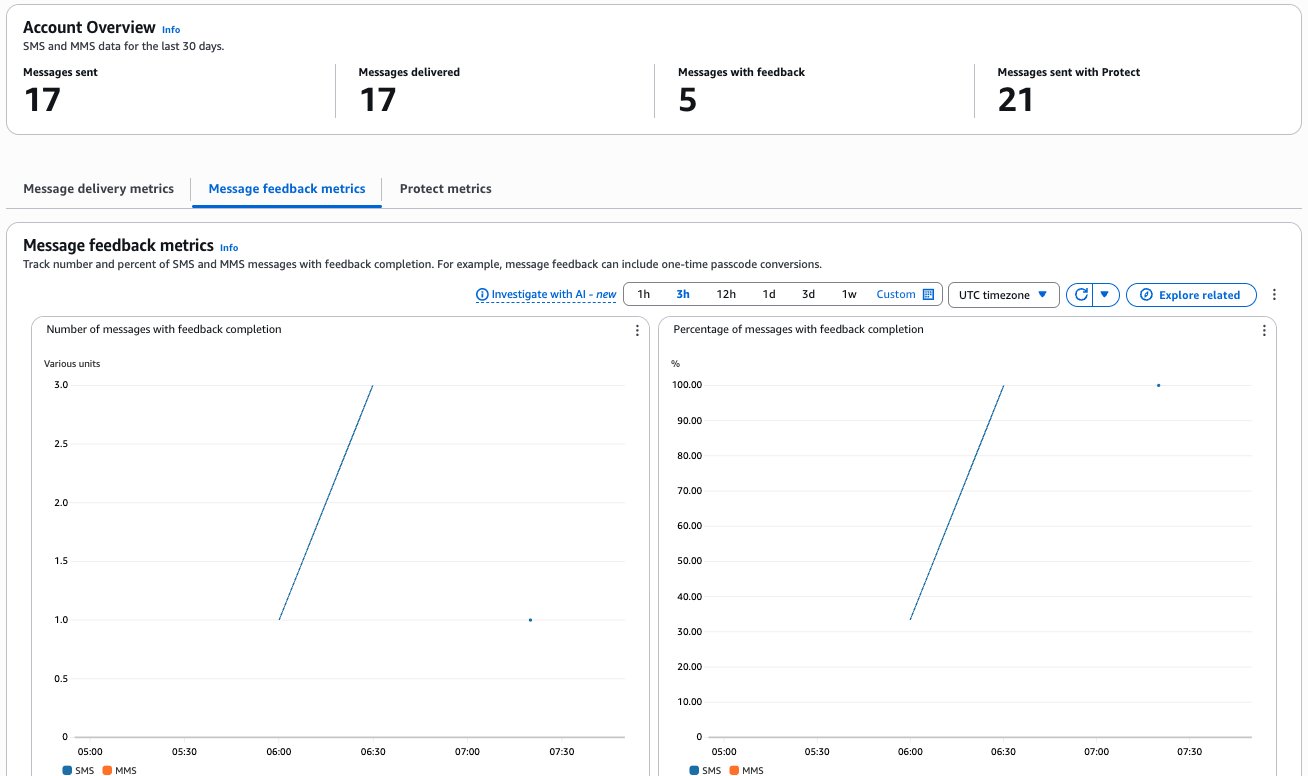
To review your application’s overall message feedback metrics, choose Dashboard in the AWS End User Messaging console navigation pane, then choose Message Feedback Metrics.

The dashboard presents three key metrics:

  • Number of messages with feedback completion – The count of SMS and MMS messages where the message feedback record is set to RECEIVED
  • Percentage of messages with feedback completion – The percentage of SMS and MMS messages where the message feedback record is set to RECEIVED
  • Number of SMS with feedback completion by country – The count of message feedback received by country

The progression to 100% completion indicates optimal system performance, where all sent OTPs were successfully received and verified by users, and the message feedback record is set to RECEIVED within the expected timeframe. This high completion rate suggests effective message delivery and a smooth user verification experience. Variations in completion rates across countries can help identify potential regional delivery challenges or user behavior patterns.

The 30% conversion starting point shown in this example is used for illustration purposes only, demonstrating messages that were intentionally left unconverted during testing.

Best practices for OTP implementation

For a secure and reliable OTP implementation, follow these best practices to balance security with user experience:

  • Include rate limiting to prevent abuse
  • Implement proper timeout mechanisms for OTPs
  • Make sure error handling provides clear feedback to users
  • Maintain comprehensive logging for security audits

Conclusion

By implementing the Message Feedback API for OTP tracking, you can gain valuable insights into your authentication system’s effectiveness in real time. This approach helps you monitor successful OTP usage and identify potential delivery issues that might affect user authentication, with granular metrics broken down by geographic regions. The data collected through message feedback offers a more accurate picture of actual user interactions compared to carrier-provided delivery receipts, helping you make data-driven decisions about your authentication system.

To build upon this foundation, consider implementing Amazon CloudWatch alerts for your conversion metrics, and optimizing your message templates based on performance data. The combination of real-time feedback, detailed analytics, and proactive monitoring can help make sure your OTP system remains both secure and efficient.

For additional implementation guidance and best practices, refer to the following resources:


About the authors

Configure seamless single sign-on with SQL analytics in Amazon SageMaker Unified Studio

Post Syndicated from Arun A K original https://aws.amazon.com/blogs/big-data/configure-seamless-single-sign-on-with-sql-analytics-in-amazon-sagemaker-unified-studio/

Amazon SageMaker Unified Studio provides a unified experience for using data, analytics, and AI capabilities. SageMaker Unified Studio now supports trusted identity propagation (TIP) for SQL workloads, enabling fine-grained data access control based on individual user identities. Organizations can use this integration to manage data permissions through AWS Lake Formation while using their existing single sign-on (SSO) infrastructure.

Organizations already using Amazon Redshift with TIP can extend their existing Lake Formation permissions to SageMaker Unified Studio. Users simply log in through SSO and access their authorized data using the SQL editor, maintaining consistent security controls across their analytics environment.

This post demonstrates how to configure SageMaker Unified Studio with SSO, set up projects and user onboarding, and access data securely using integrated analytics tools.

Solution overview

For our use case, a retail corporation is planning to implement sales analytics to identify sales patterns and product categories that are doing well. This will help the sales team improve on sales planning with targeted promotions and help the finance team plan budgeting with better inventory management. The corporation stores a customer table in an Amazon Simple Storage Service (Amazon S3) data lake and a store_sales table in a Redshift cluster.

The corporation uses SageMaker Unified Studio as the UI, with users onboarded from their identity provider (IdP) to AWS IAM Identity Center with TIP. Amazon SageMaker Lakehouse centralizes data from Amazon S3 and Amazon Redshift, and Lake Formation provides fine-grained access control based on user identity. For our example use case, we explore two different users. The following table summarizes their roles, the tools they use, and their data access.

User Group Tool Data Access
Ethan (Data Analyst) Sales Amazon Athena for interactive SQL analysis Non-sensitive customer data (id, c_country, birth_year) and store_sales full table access
Frank (BI Analyst) Finance Amazon Redshift for reports and visualization US customer data (c_country='US')

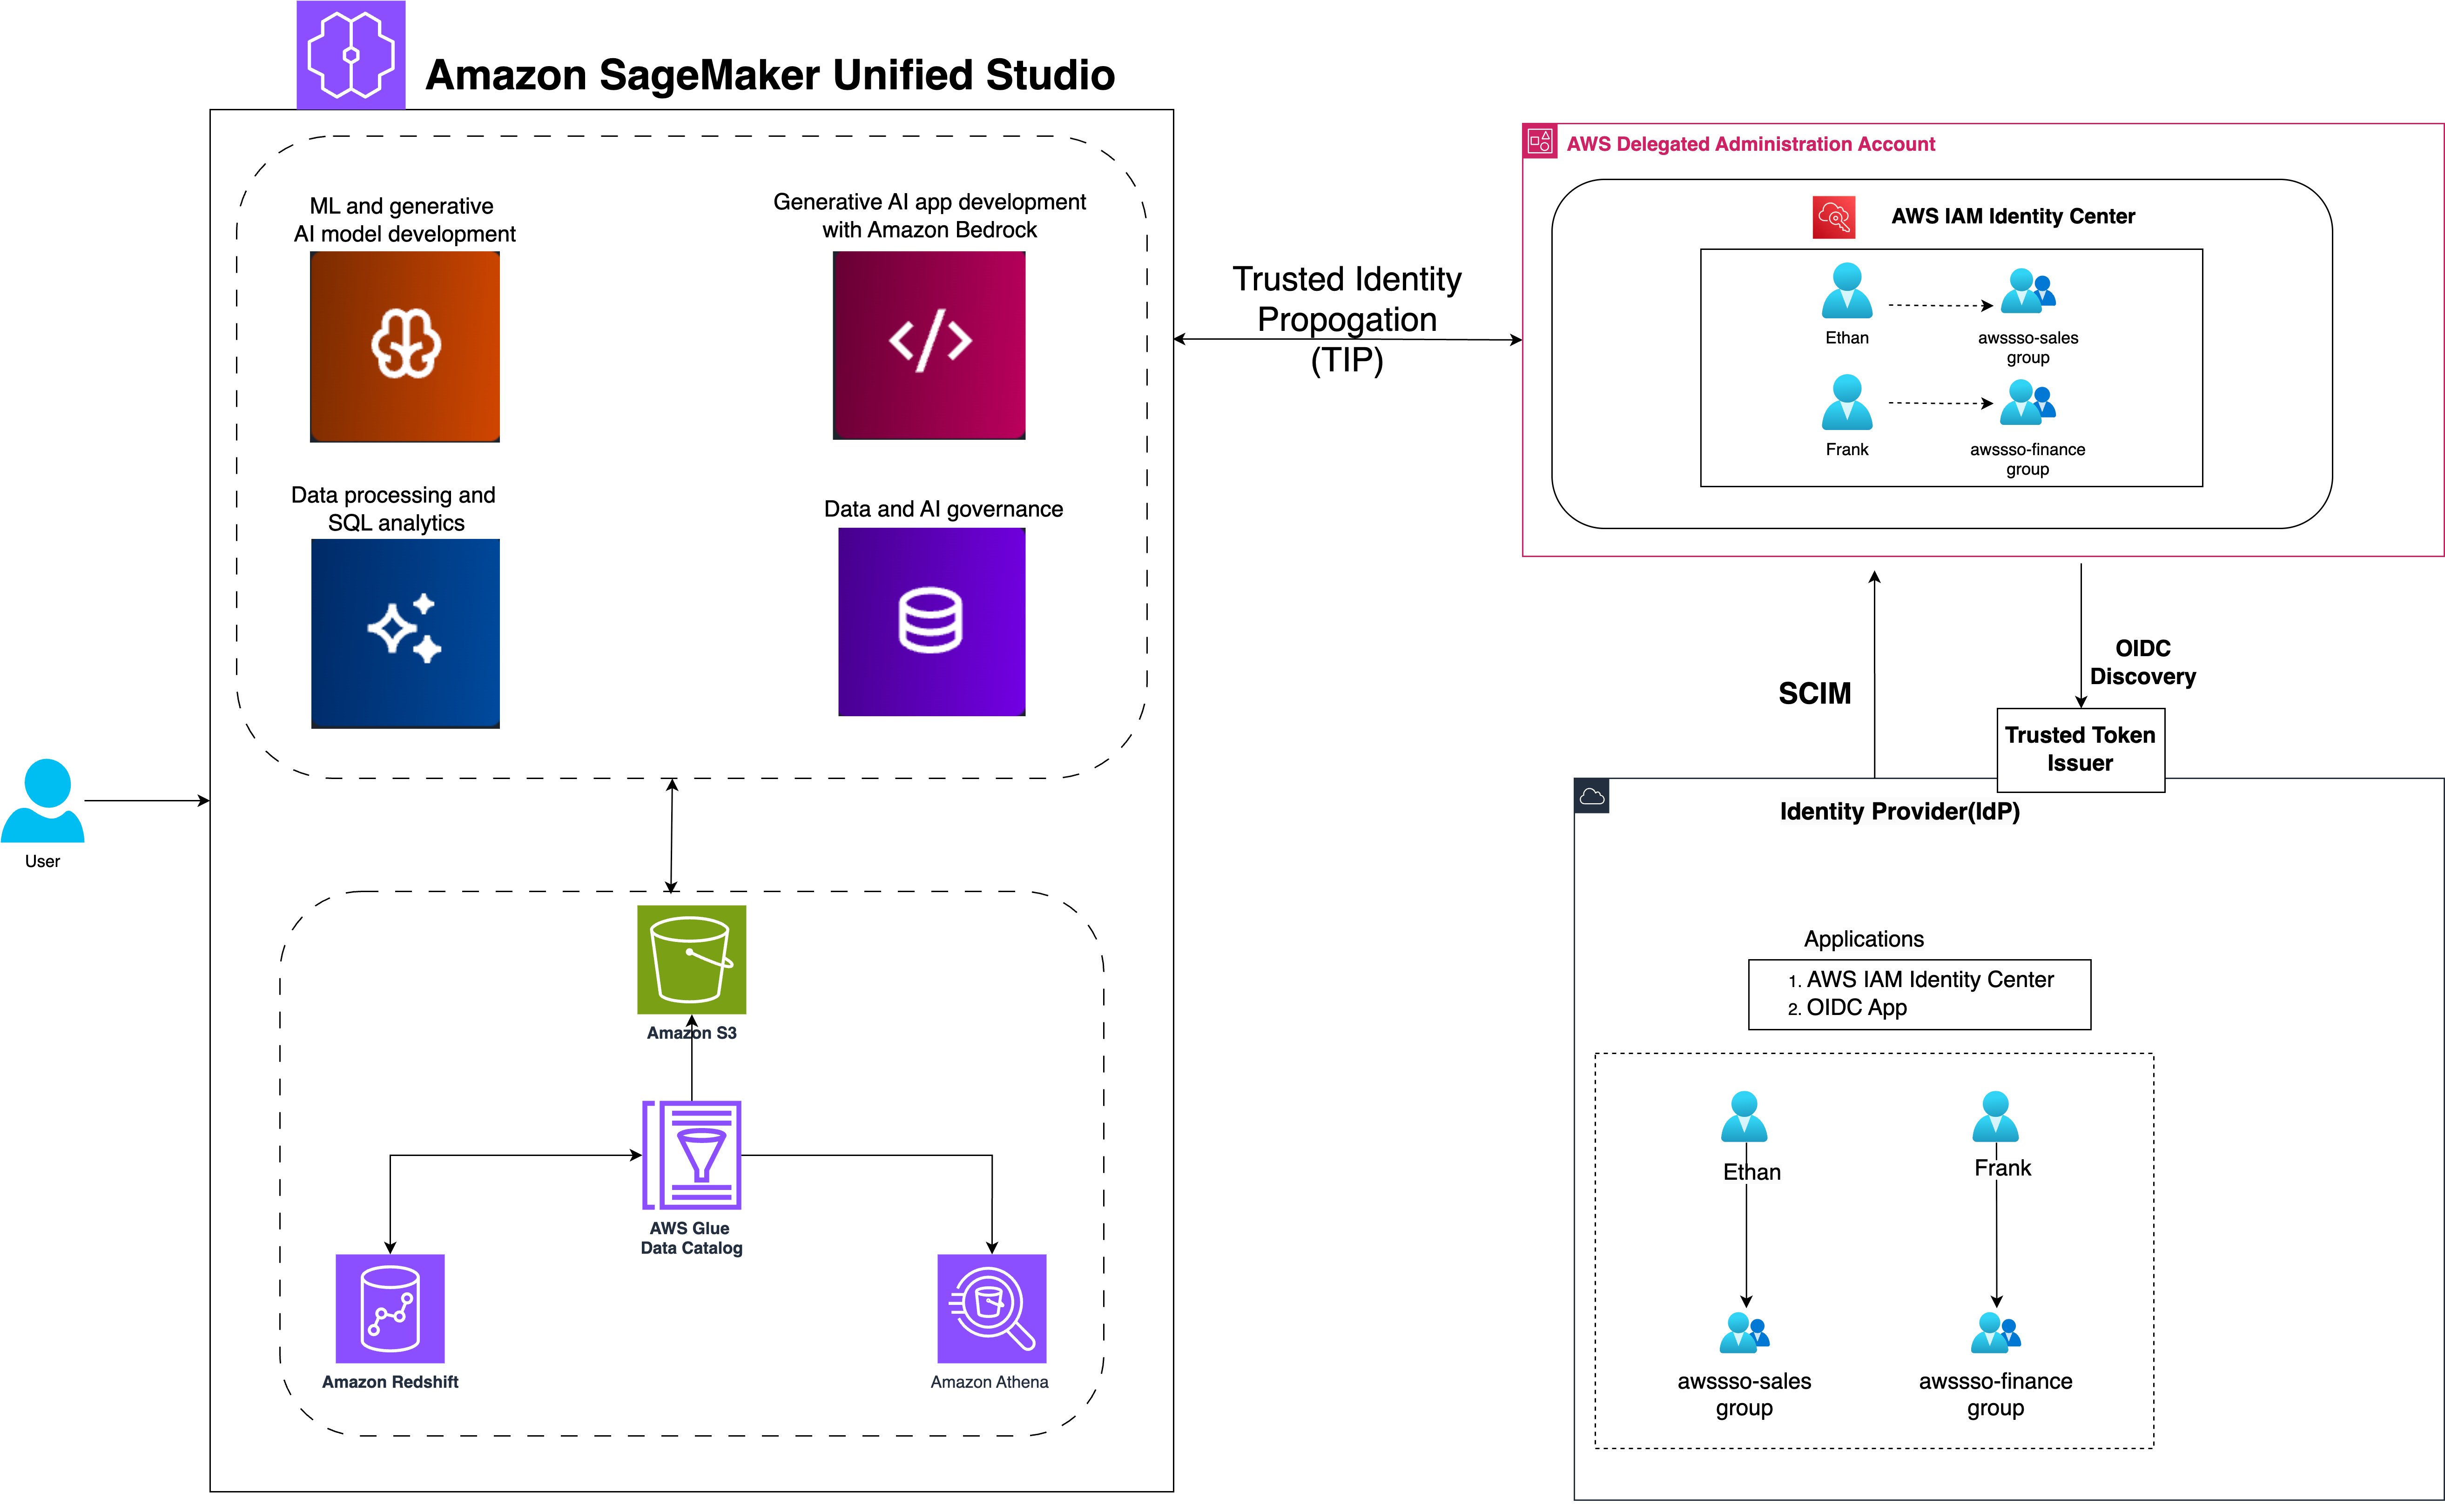
The following diagram illustrates the solution architecture.

SageMaker Unified Studio with IAM Identity Center simplifies the user journey from authentication to data analysis. The workflow consists of the following steps:

  1. Users sign in with organizational SSO credentials through their IdP and are redirected to SageMaker Unified Studio.
  2. Users configure IAM Identity Center authentication for Amazon Redshift, linking identity management with data access.
  3. Users access the query editor for Amazon Redshift or SageMaker Lakehouse, triggering IAM Identity Center federation to generate session and access tokens.
  4. SageMaker Unified Studio retrieves user authorization details and group membership using the session token.
  5. Users are authenticated as IAM Identity Center users, ready to explore and analyze data using Amazon Redshift and Amazon Athena.

To implement our solution, we walk through the following high-level steps:

  1. Set up SageMaker Lakehouse resources.
  2. Create a SageMaker Unified Studio domain with SSO and TIP enabled.
  3. Configure Amazon Redshift for TIP and validate access.
  4. Validate data access using Amazon Athena.

Prerequisites

Before you begin implementing the solution, you must have the following in place:

  1. If you don’t have an AWS account, you can sign up for one.
  2. We provide utility scripts to help set up various sections of the post. To use them:
    1. Right-click this link and save the utility scripts zip file.
    2. Unzip the file to a terminal that has the AWS Command Line Interface (AWS CLI) configured. You can also use AWS CloudShell.
    3. Run the scripts only when prompted in the relevant sections.
    Note: The utility scripts are configured for
    us-east-1 region. If you prefer another region, edit the region in the scripts before running them.
  3. To deploy the infrastructure, right-click this link and select ‘Save Link As’ to save it as sagemaker-unified-studio-infrastructure.yaml. Then upload the file when creating a new stack in the AWS CloudFormation console, which will create the following resources:
    1. An S3 bucket to hold the customer data used in this post.
    2. An AWS Identity and Access Management (IAM) role called DataTransferRole with permissions as defined in Prerequisites for managing Amazon Redshift namespaces in the AWS Glue Data Catalog.
    3. An IAM role called IAMIDCRedshiftRole, which will be used later to set up the IAM Identity Center Redshift application.
    4. An IAM role called LakeFormationRegistrationRole, following the instructions in Requirements for roles used to register locations, and necessary IAM policies.
  4. If you don’t have a Lake Formation user, you can create one. For this post, we use an admin user. For instructions, see Create a data lake administrator.
  5. If IAM Identity Center is not enabled, refer to Enabling AWS IAM Identity Center for instructions to enable it.
    1. If you need to migrate existing Redshift users and groups, use the IAM Identity Center Redshift migration utility.
    2. For a quick way to test the feature and familiarize yourself with the process, we provide a script to generate mock users and groups. Run the setup-idc.sh script, which is provided in Step 2, to create test users and groups in IAM Identity Center for demonstration purposes.
  6. Integrate IAM Identity Center with Lake Formation. For instructions, see Connecting Lake Formation with IAM Identity Center.
  7. Register the S3 bucket as a data lake location:
    1. On the Lake Formation console, choose Data lake locations in the navigation pane.
    2. Choose Register location.
    3. For the role, use LakeFormationRegistrationRole.
  8. Create an IAM Identity Center Redshift application, as detailed in our previous post:
    1. On the Amazon Redshift console, choose IAM Identity Center connections in the navigation pane and choose Create application.
    2. For both the display name and application name, enter redshift-idc-app.
    3. Set the IdP namespace to awsidc.
    4. Choose IAMIDCRedshiftRole as the IAM role.
    5. Choose Next to create the application.
    6. Take note of the application Amazon Resource Name (ARN) to use in subsequent steps. The ARN format is arn:aws:sso::<ACCOUNT_NUMBER>:application/ssoins-<RANDOM_STRING>/apl-<RANDOM_STRING>.
  9. If you don’t have existing Redshift tables to work with, run the script setup-producer-redshift.sh, which is provided in Step 2, to create a producer namespace and workgroup, set up a sample sales database, and generate necessary tables with test data.
  10. The post also uses simulated customer data stored in the AWS Glue Data Catalog. To set up this data and configure the necessary Lake Formation permissions, run the setup-glue-tables-and-access.sh script provided in Step 2.

Set up SageMaker Lakehouse resources

In this section, we configure the foundational lakehouse resources required for SageMaker to access and analyze data across multiple storage systems. We’ll register the Redshift instance to the AWS Glue Data Catalog to make warehouse data discoverable and establish Lake Formation permissions on lakehouse resources for user identities to ensure secure, governed access to both data lake and data warehouse resources from within SageMaker environments.

Register Redshift instance to the Data Catalog

In this step, we use the store_sales data, which we created earlier using the setup-producer-redshift.sh script. You can register entire clusters to the Data Catalog and create catalogs managed by AWS Glue. To register a cluster to the Data Catalog, complete the following steps:

  1. On the Lake Formation console, choose Administrative roles and tasks in the navigation pane.
  2. Under Data lake administrators, choose Add.
  3. Choose Read-only administrator, then choose AWSServiceRoleForRedshift.
  4. On the Amazon Redshift console, open your namespace.
  5. On the Actions dropdown menu, chose Register with AWS Glue Data Catalog, then choose Register.
  6. Sign in to the Lake Formation console as the data lake administrator and choose Catalogs in the navigation pane.
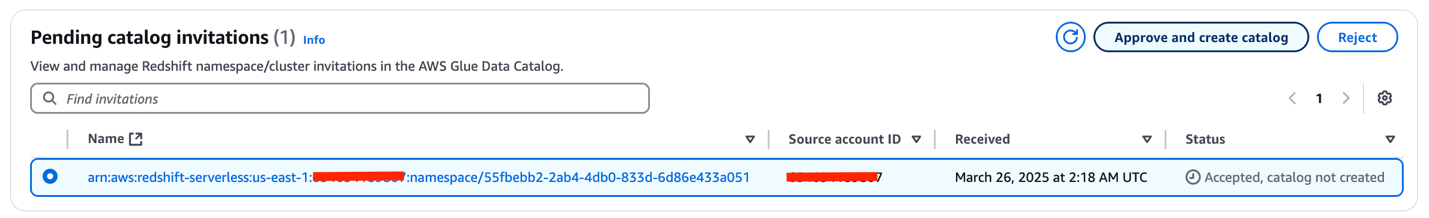
  7. Under Pending catalog invitations, select the namespace and accept the invitation by choosing Approve and create catalog.
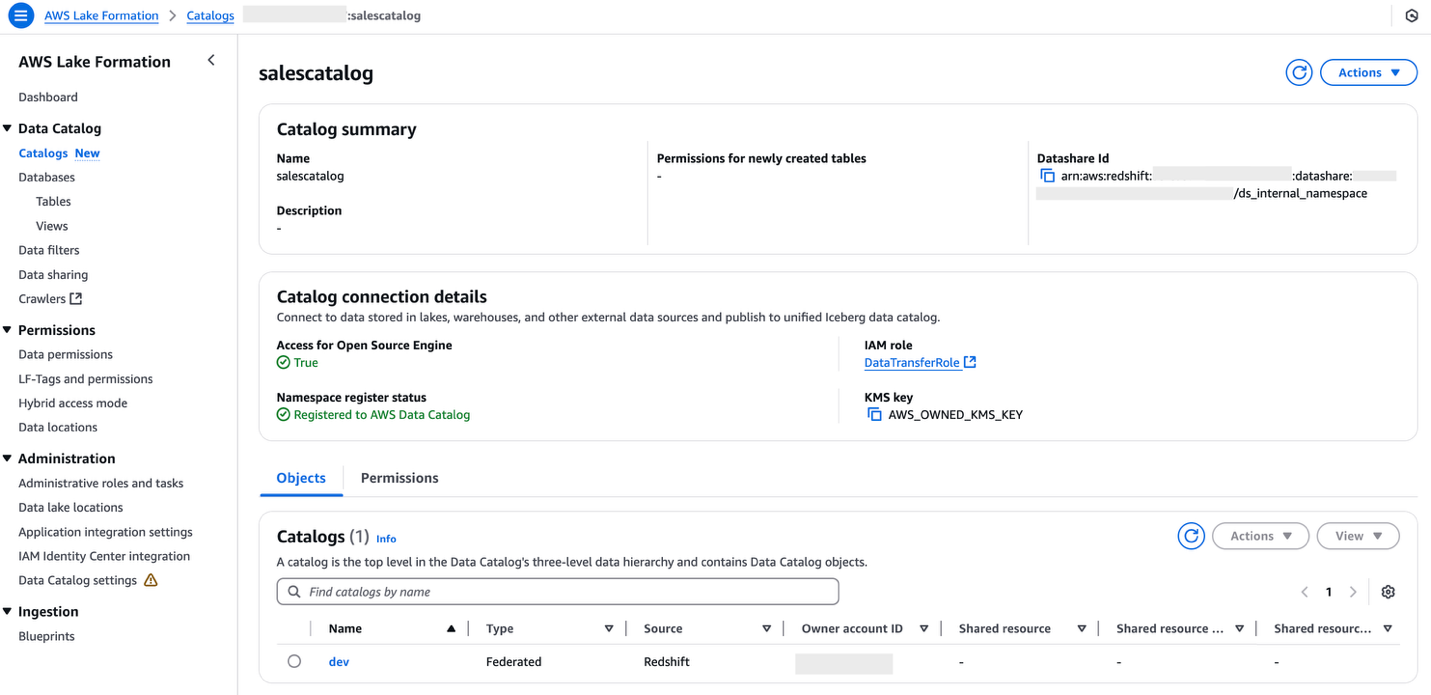
  8. Provide the name for the catalog as salescatalog.
  9. Select Access this catalog from Apache Iceberg compatible engines, choose DataTransferRole for the IAM role, then choose Next.
  10. Choose Add permissions and choose the admin IAM role under IAM users and roles.
  11. Select Super user for catalog permissions and choose Add.
  12. Choose Next.
  13. Choose Create catalog.

Set up Lake Formation permission on lakehouse resources for user identities

In this section, we configure Lake Formation permissions to enable secure access to lakehouse resources for federated user identities. Lake Formation provides fine-grained access control that works seamlessly with IAM Identity Center, allowing you to manage permissions centrally while maintaining security boundaries.

We’ll focus on granting database access to IAM Identity Center groups in Lake Formation and setting table-level permissions for federated Redshift catalog tables. These permissions form the security foundation for our federated query architecture, enabling users to seamlessly access both S3 data lake and Redshift data warehouse resources through a unified interface.

Grant database access to IAM Identity Center groups in Lake Formation

After you share your Redshift catalog with the Data Catalog and integrate with Lake Formation, you must grant appropriate database access. Follow these steps to set up permissions on your data lake resources for corporate identities:

  1. On the Lake Formation console, under Permissions in the navigation pane, choose Data permissions.
  2. Choose Grant.
  3. Select Principals for Principal type.
  4. Under Principals, select IAM Identity Center and choose Add.
  5. In the pop-up window, if this is your first time assigning users and groups, choose Get started.
  6. Search for and select the IAM Identity Center groups awssso-sales and awssso-finance.
  7. Choose Assign.
  8. Under LF-Tags or catalog resources, choose Named Data Catalog resources.
    1. Choose <accountid>:salescatalog/dev for Catalogs.
    2. Choose sales_schema for Database.
  9. Under Database permissions, select Describe.
  10. Choose Grant to apply the permissions.

Grant table-level permissions for federated Redshift catalog tables

Complete the following steps to grant table permissions to the IAM Identity Center groups:

  1. On the Lake Formation console, under Permissions in the navigation pane, choose Data permissions.
  2. Choose Grant.
  3. Select Principals for Principal type.
  4. Under Principals, select IAM Identity Center and choose Add.
  5. In the pop-up window, if this is your first time assigning users and groups, choose Get started.
  6. Search for and select the IAM Identity Center group awssso-sales.
  7. Choose Assign.
  8. Under LF-Tags or catalog resources, choose Named Data Catalog resources.
    1. Choose <accountid>:salescatalog/dev for Catalogs.
    2. Choose sales_schema for Database.
    3. Choose store_sales for Table.
  9. Select Select and Describe for Table permissions.
  10. Choose Grant to apply the permissions.

Create a SageMaker Unified Studio domain with SSO and TIP enabled

For instructions to create a SageMaker Unified Studio domain, refer to Create an Amazon SageMaker Unified Studio domain – quick setup. Because your IAM Identity Center integration is already complete, you can specify an IAM Identity Center user in the domain configuration settings.

Enable TIP in SageMaker Unified Studio

Complete the following steps to enable TIP in SageMaker Unified Studio:

  1. On the SageMaker console, use the AWS Region selector in the top navigation bar to choose the appropriate Region.
  2. Choose View domains and choose the domain’s name from the list.
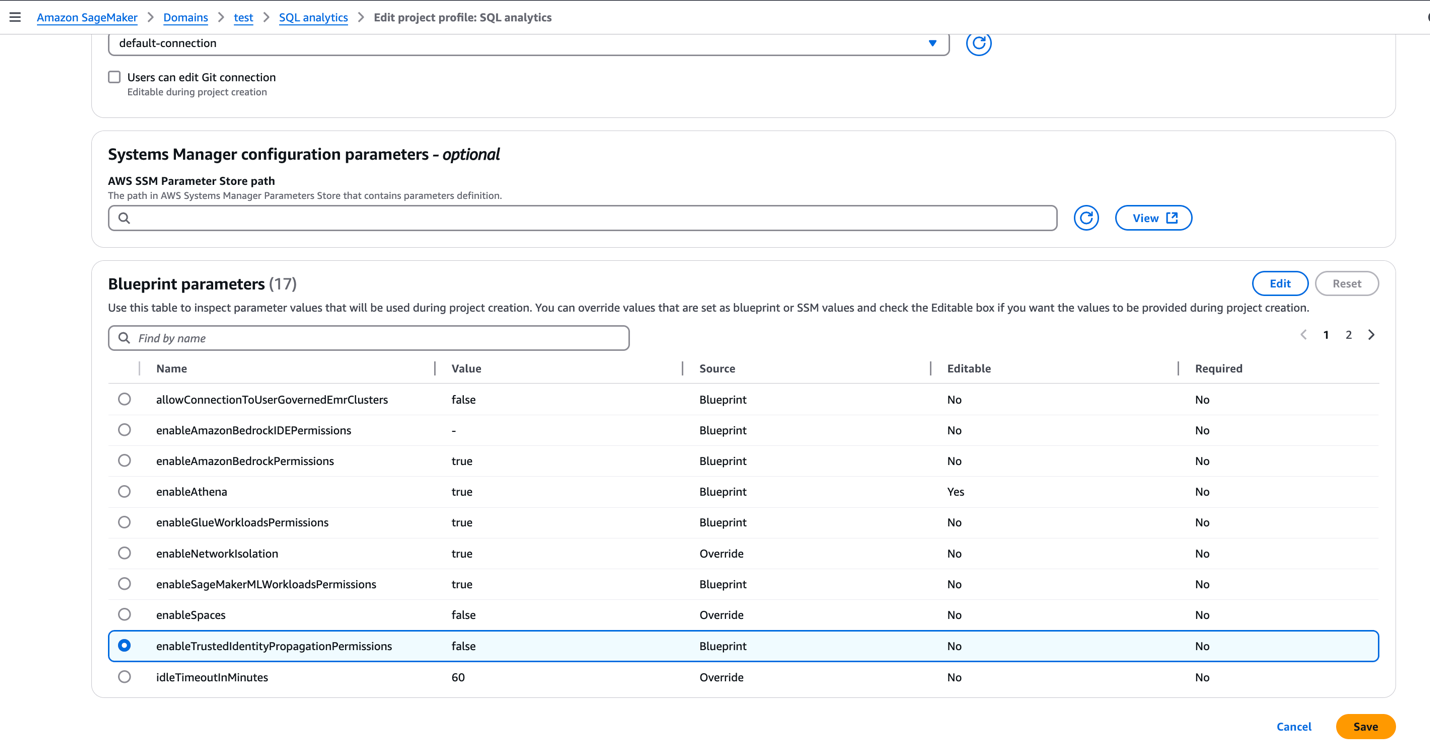
  3. On the domain’s details page, on the Project profiles tab, choose a project profile, for example, SQL analytics.
  4. Select SQL analytics and choose Edit.
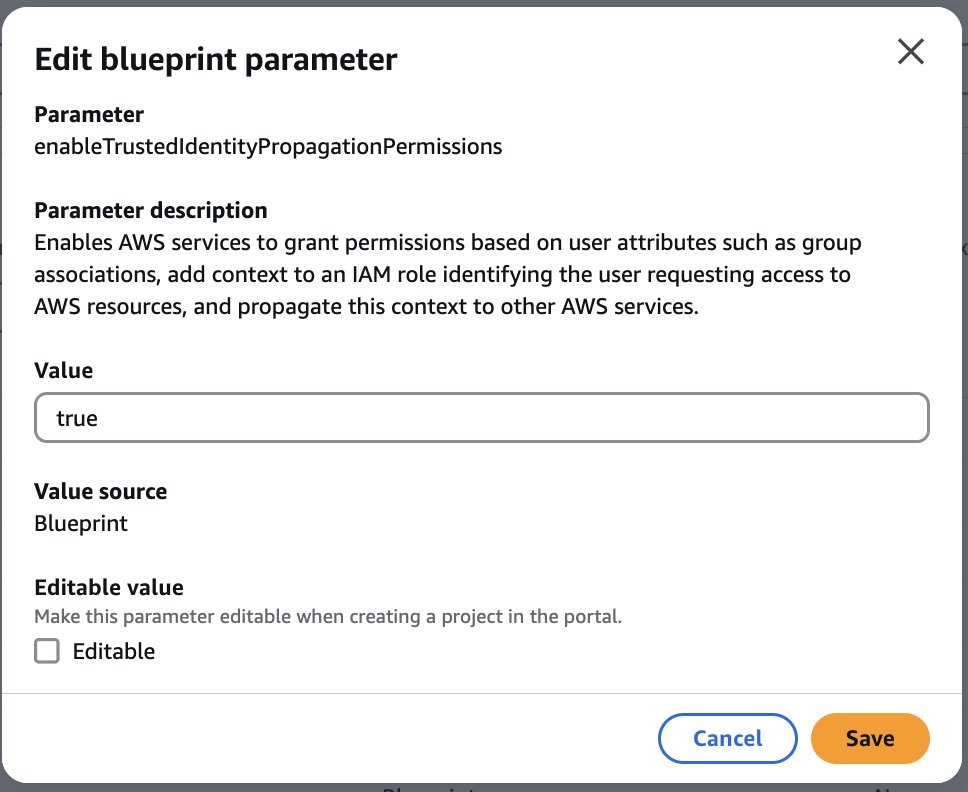
  5. In the Blueprint parameters section, select enableTrustedIdentityPropagationPermissions and choose Edit.
  6. Update the value as true.
  7. To enforce authorization-based on TIP, the SageMaker Unified Studio admin can make this parameter non-editable.
  8. Choose Save.

Enable user access for SageMaker Unified Studio domain

Complete the following steps to enable user access for the SageMaker Unified Studio domain:

  1. Open the SageMaker console in the appropriate Region and choose Domains in the navigation pane.
  2. Choose an existing SageMaker Unified Studio domain where you want to add SSO user access.
  3. On the domain’s details page, on the User management tab, in the Users section, choose Add and Add SSO users and groups.
  4. Choose the user (for this post, we add the user Frank) from the dropdown list and choose Add users and groups.

Add project members

SageMaker Unified Studio projects facilitate team collaboration for different business initiatives. As the project owner, Ethan now can add Frank as a team member to enable their collaboration. To add members to an existing project, complete the following steps:

  1. Sign in to the SageMaker Unified Studio console using the SSO credentials of who owns the project (for this post, Ethan).
  2. Choose Select a project.
  3. Choose the project you want to edit.
  4. On the Project overview page, expand Actions and choose Manage members.
  5. Choose Add members.
  6. Enter the name of the user or group you want to add (for this post, we add Frank).
  7. Select Contributor if you want to add the project member as a contributor.
  8. (Optional) Repeat these steps to add more project members. You can add up to eight project members at a time.
  9. Choose Add members.

Create a SQL analytics project in Unified Studio

In this step, we federate into SageMaker Unified Studio and create a project using SQL analytics. Complete the following steps:

  1. Federate into SageMaker Unified Studio using your IAM Identity Center credentials:
    1. On the SageMaker console, choose Domains in the navigation pane.
    2. Copy the SageMaker Unified Studio URL for your domain and enter it into a new browser window.
    3. Choose Sign in with SSO.
    4. A browser pop-up will redirect you to your preferred IdP login page, where you enter your IdP credentials.
    5. If authentication if successful, you will be redirected to SageMaker Unified Studio.
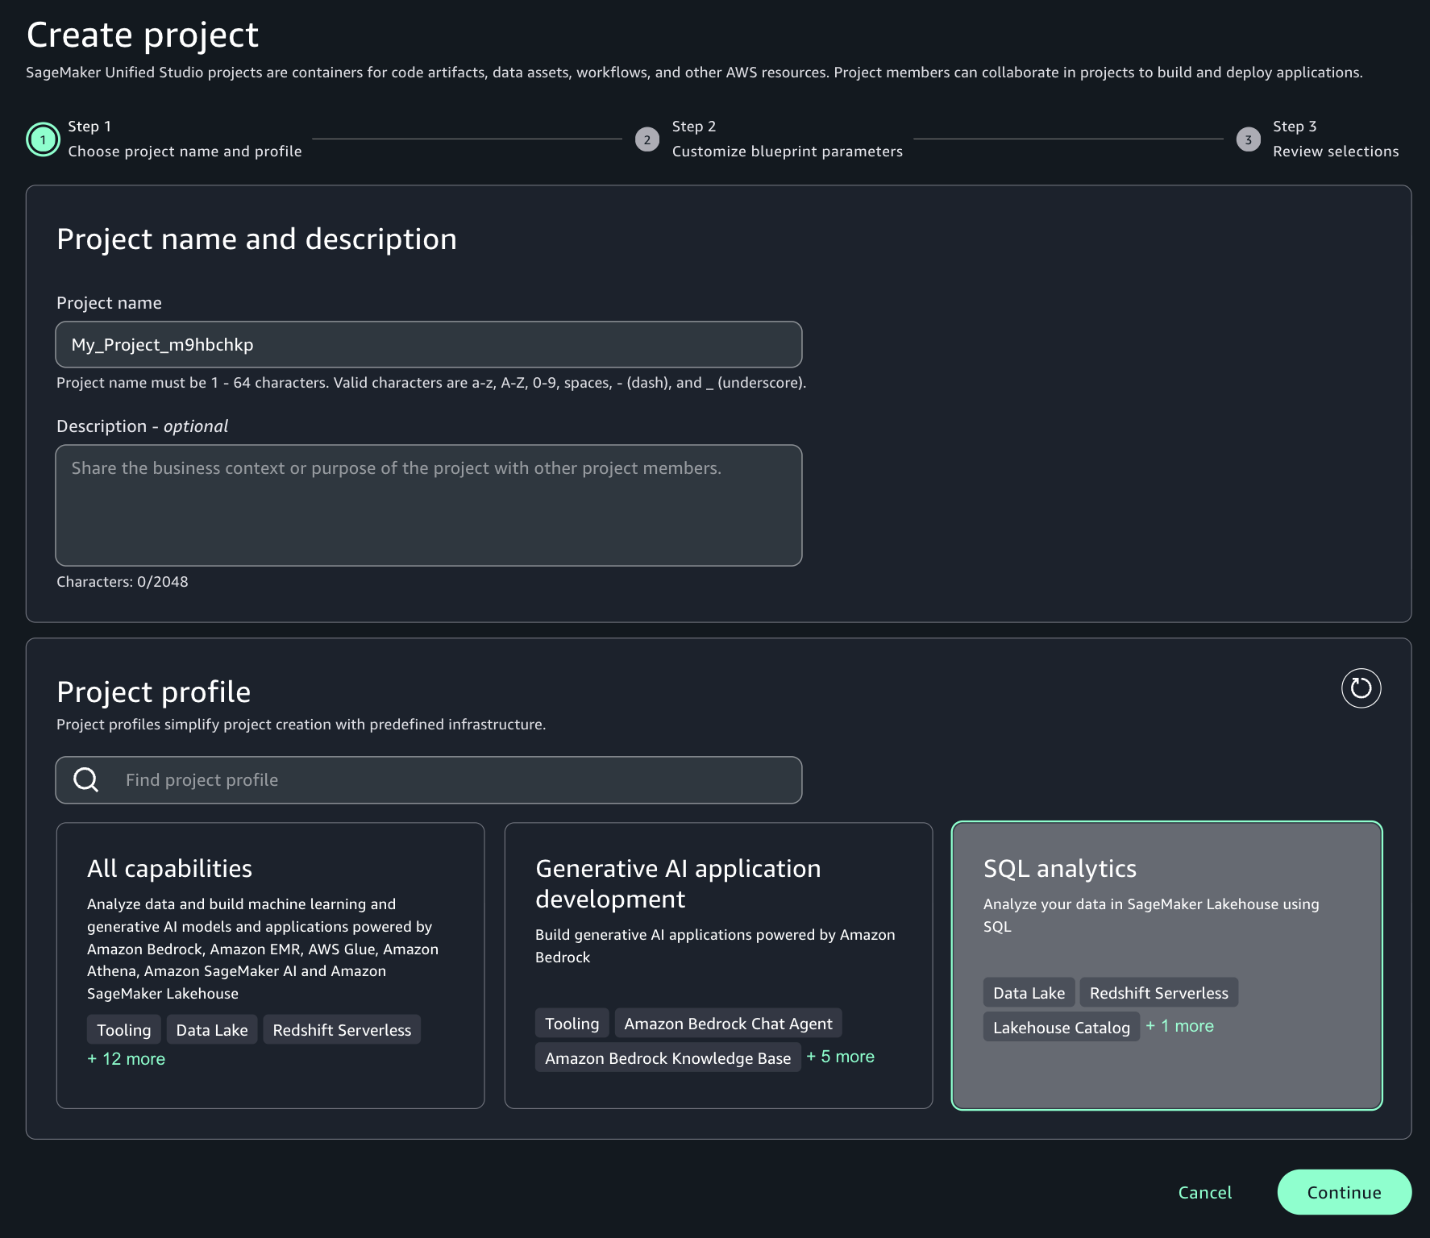
  2. After logging in, choose Create project.
  3. Enter a name for your project. This project name is final and can’t be changed later.
  4. (Optional) Enter a description for your project. You can edit this later.
  5. Choose a project profile. For this demo, we choose the SQL analytics profile from the available templates.
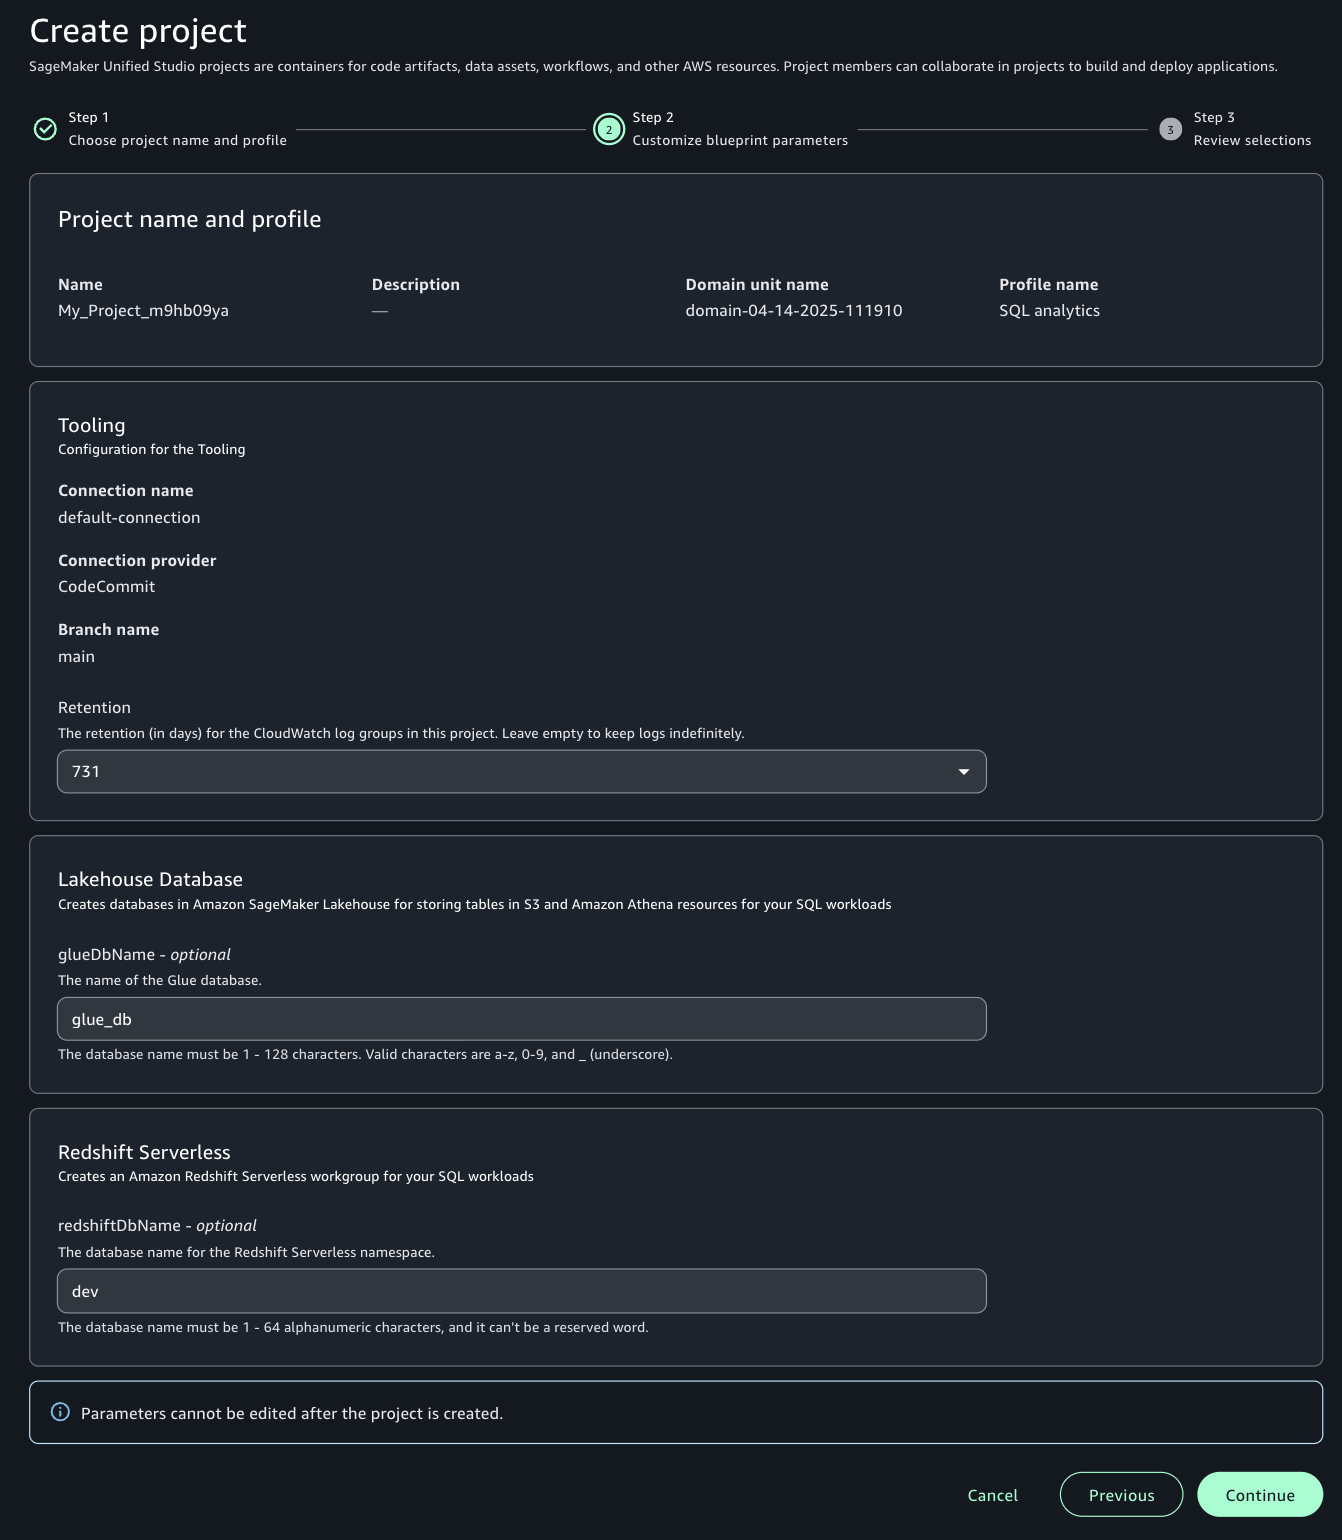
  6. Leave the default values as they are or modify them according to your use case, then choose Continue.
  7. Choose Create project to finalize the project and initialize your SQL analytics workspace.

For more detailed information and advanced configurations, refer to Create a project.

Configure Amazon Redshift for TIP and validate access

Run the setup-consumer-redshift.sh script (provided in the prerequisites). This script will create a new namespace and workgroup and add the required tags, which you will use later to integrate with SageMaker Unified Studio compute.

If you are creating the cluster manually, add one of the following tags to the Redshift cluster or workgroup that you want to add to SageMaker Unified Studio:

  • Option 1 – Add a tag to allow only a specific SageMaker Unified Studio project to access it: AmazonDataZoneProject=<projectID>
  • Option 2 – Add a tag to allow all SageMaker Unified Studio projects in this account to access it: for-use-with-all-datazone-projects=true

Create compute using IAM Identity Center authentication

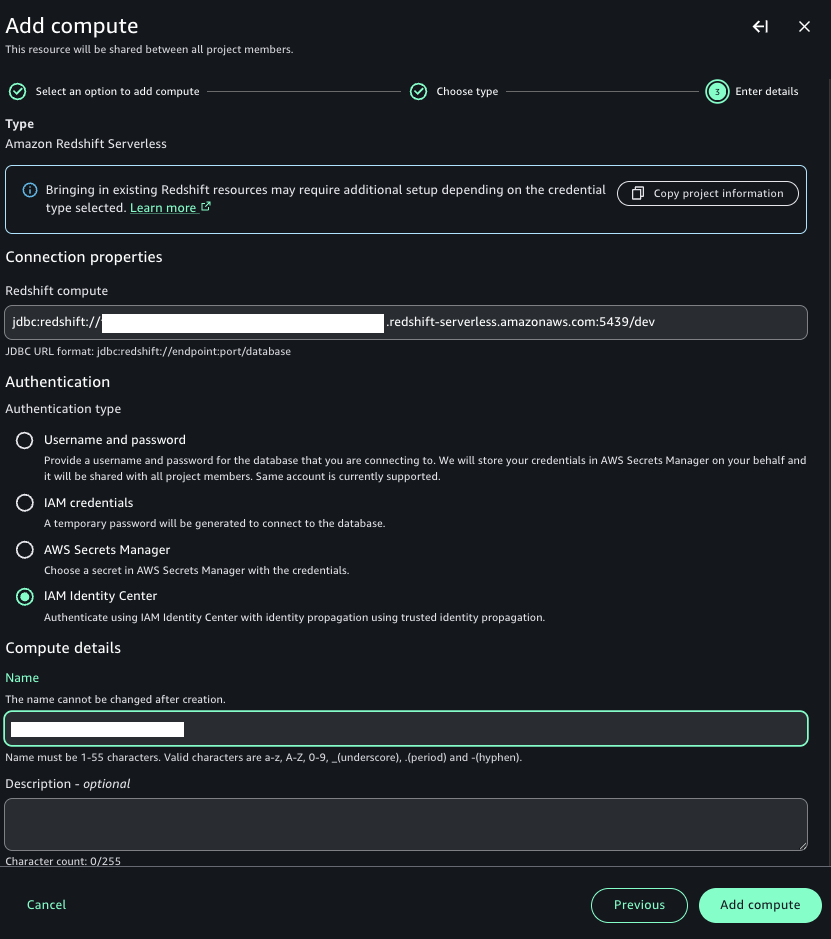
After you set up your project, the next step is to establish a compute resource connection on the SageMaker Unified Studio console. Follow these steps to add either Amazon Redshift Serverless or a provisioned cluster to your project environment:

  1. Go to the Compute section of your project in SageMaker Unified Studio.
  2. On the Data warehouse tab, choose Add compute.
  3. You can create a new compute resource or choose an existing one. For this post, we choose Connect to existing compute resources, then choose Next.
  4. Choose the type of compute resource you want to add, then choose Next. For this post, we choose Redshift Serverless.
  5. Under Connection properties, provide the JDBC URL or the compute you want to add, which is integrated with IAM Identity Center. If the compute resource is in the same account as your SageMaker Unified Studio project, you can select the compute resource from the dropdown menu. In our example, we use the consumer account that was just provisioned.
  6. Under Authentication, select IAM Identity Center.
  7. For Name, enter the name of the Redshift Serverless or provisioned cluster you want to add.
  8. For Description, enter a description of the compute resource.
  9. Choose Add compute.

The SageMaker Unified Studio Project Compute and Data pages will now display information for that resource.

If everything is configured correctly, your compute will be created using IAM Identity Center. Because your IdP credentials are already cached while you’re logged in to SageMaker Unified Studio, it uses the same credentials and creates the compute.

Test data access using Amazon Redshift

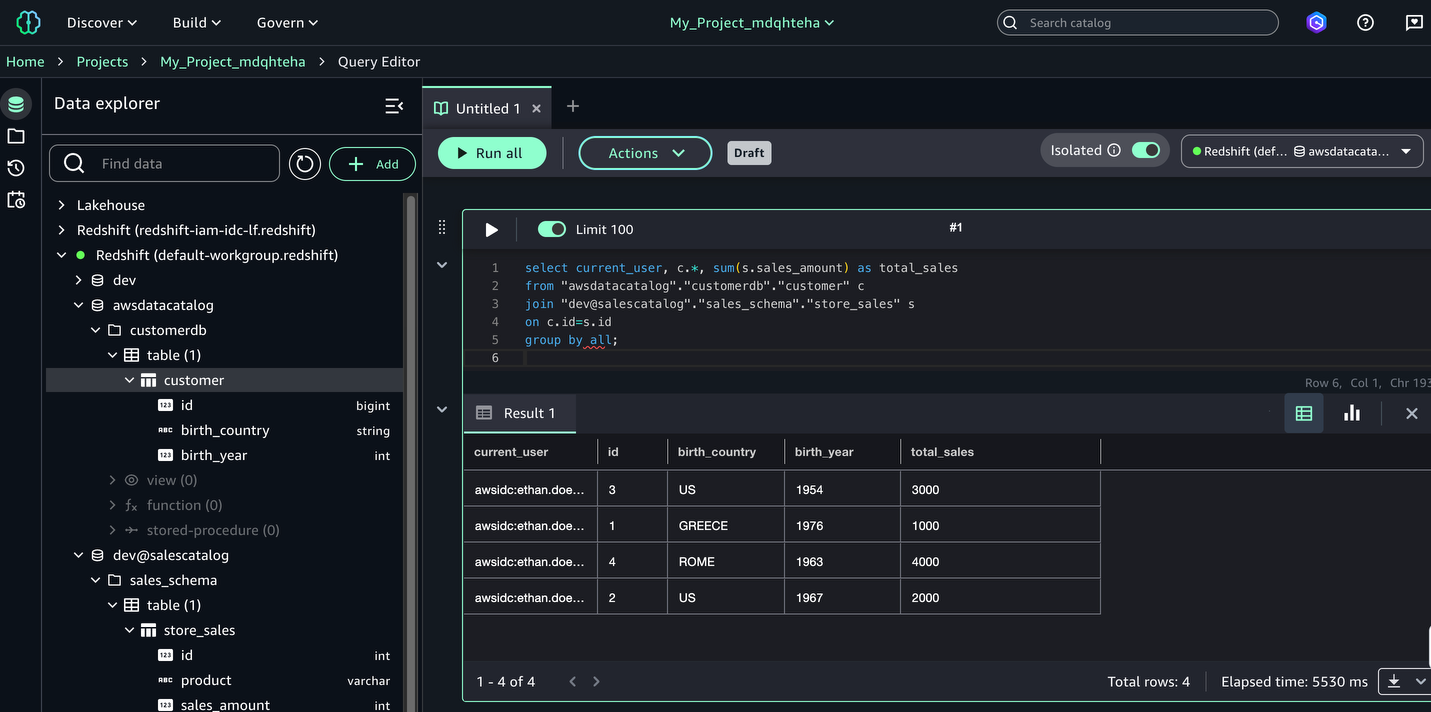
When Ethan logs in to SageMaker Unified Studio using IAM Identity Center authentication, he successfully federates and can access customer data from all countries but only for non-sensitive columns. Let’s connect to Amazon Redshift in SageMaker Unified Studio by following these steps:

  1. Choose Actions and choose Open Query editor.
  2. Choose Redshift in the Data explorer pane.
  3. Run the customer sales calculation query to observe that user Ethan (a data analyst) can access customer data from all countries but only non-sensitive columns (id, birth_country, product_id):
    select current_user, c.*, sum(s.sales_amount) as total_sales
    from "awsdatacatalog"."customerdb"."customer" c
    join "dev@salescatalog"."sales_schema"."store_sales" s 
    on c.id=s.id
    group by all;

You have successfully configured Redshift to use IAM Identity Center authentication in SageMaker Unified Studio.

Validate data access using Amazon Athena

When Frank logs in to SageMaker Unified Studio using IAM Identity Center authentication, he successfully federates and can access customer data only for the United States. To query with Athena, complete the following steps:

  1. Choose Actions and choose Open Query editor.
  2. Choose Lakehouse in the Data explorer pane.
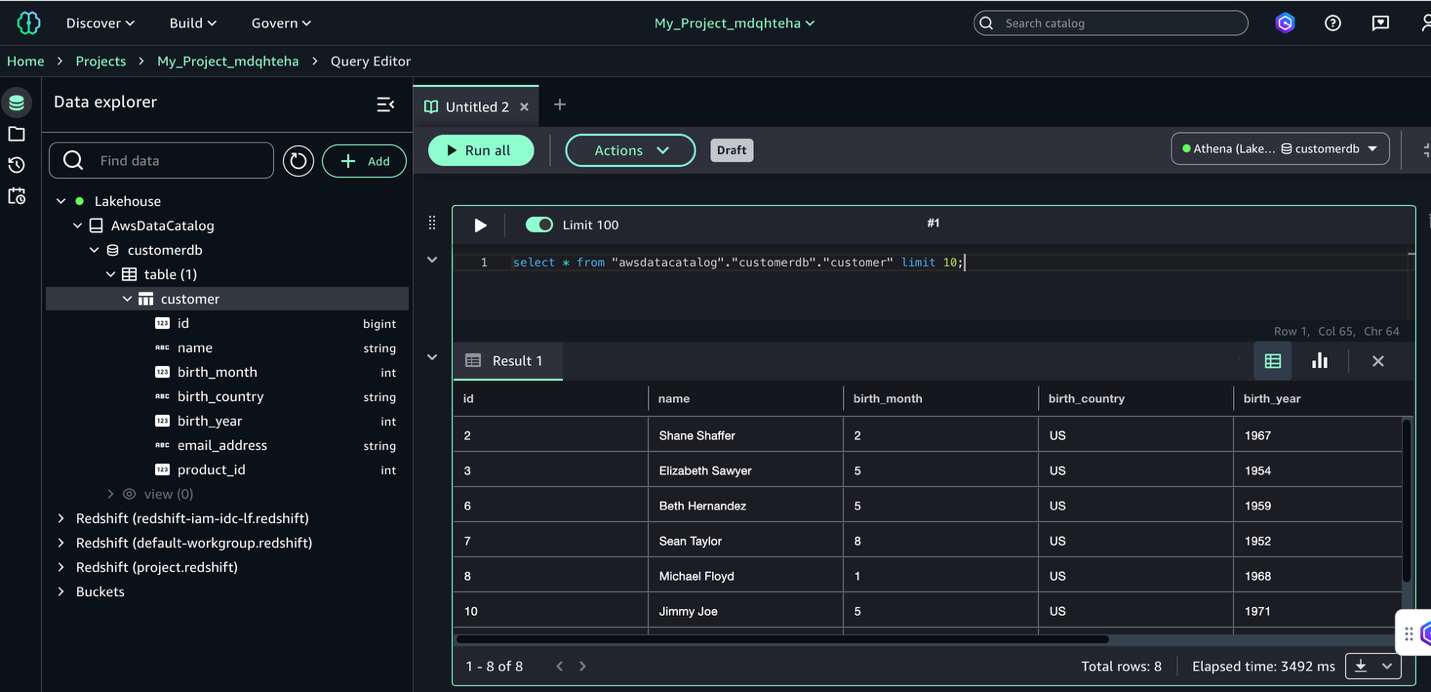
  3. Explore AwsDataCatalog, expand the database, choose the respective table, and on the options menu (three dots), choose Preview data.

The following demonstration illustrates how user Frank, a BI analyst, can perform SQL analysis using Athena. Due to row-level filtering implemented through Lake Formation, Frank’s access is restricted to customer data from the United States only. Additionally, you can observe that in the Data explorer pane, Frank can only view the customerdb database. The dev@salescatalog database is not visible to Frank because no access has been granted to his respective group from Lake Formation.

The IAM Identity Center authentication integration is complete; you can use both Amazon Redshift and Athena through SageMaker Unified Studio in a simplified, all-in-one interface.Note that, at the time of writing, Athena doesn’t work with Redshift Managed Storage (RMS).

Clean up

Complete the following steps to clean up the resources you created as part of this post:

  1. Delete the data from the S3 bucket.
  2. Delete the Data Catalog objects.
  3. Delete the Lake Formation resources and Athena account.
  4. Delete the SageMaker Unified Studio project and associated domain.
  5. If you created new Redshift cluster for testing this solution, delete the cluster.

Conclusion

In this post, we provided a comprehensive guide to enabling trusted identity propagation within SageMaker Unified Studio. We covered the setup of a SageMaker Unified Studio domain with SSO, the creation of tailored projects, efficient user onboarding with appropriate permissions, and the management of AWS Glue and Amazon Redshift managed catalog permissions using Lake Formation. Through practical examples, we demonstrated how to use both Amazon Redshift and Athena within SageMaker Unified Studio, showcasing secure data access and analysis capabilities. This approach helps organizations maintain strict identity controls while helping data scientists and analysts derive valuable insights from both data lake and data warehouse environments, supporting both security and productivity in machine learning workflows.

For more information on this integration, refer to Trusted identity propagation.


About the authors

Maneesh Sharma

Maneesh Sharma

Maneesh is a Sr. Architect at AWS with 15 years of experience designing and implementing large-scale data warehouse and analytics solutions. He works closely with customers to help them modernize their legacy applications to AWS cloud-based platforms.

Srividya Parthasarathy

Srividya Parthasarathy

Srividya is a Senior Big Data Architect with Amazon SageMaker Lakehouse. She works with the product team and customers to build robust features and solutions for their analytical data platform. She enjoys building data mesh solutions and sharing them with the community.

Arun A K

Arun A K

Arun is a Senior Big Data Specialist Solutions Architect at Amazon Web Services. He helps customers design and scale data platforms that power innovation through analytics and AI. Arun is passionate about exploring how data and emerging technologies can solve real-world problems. Outside of work, he enjoys sharing knowledge with the tech community and spending time with his family.

Zero downtime blue/green deployments with Amazon API Gateway

Post Syndicated from Biswanath Mukherjee original https://aws.amazon.com/blogs/compute/zero-downtime-blue-green-deployments-with-amazon-api-gateway/

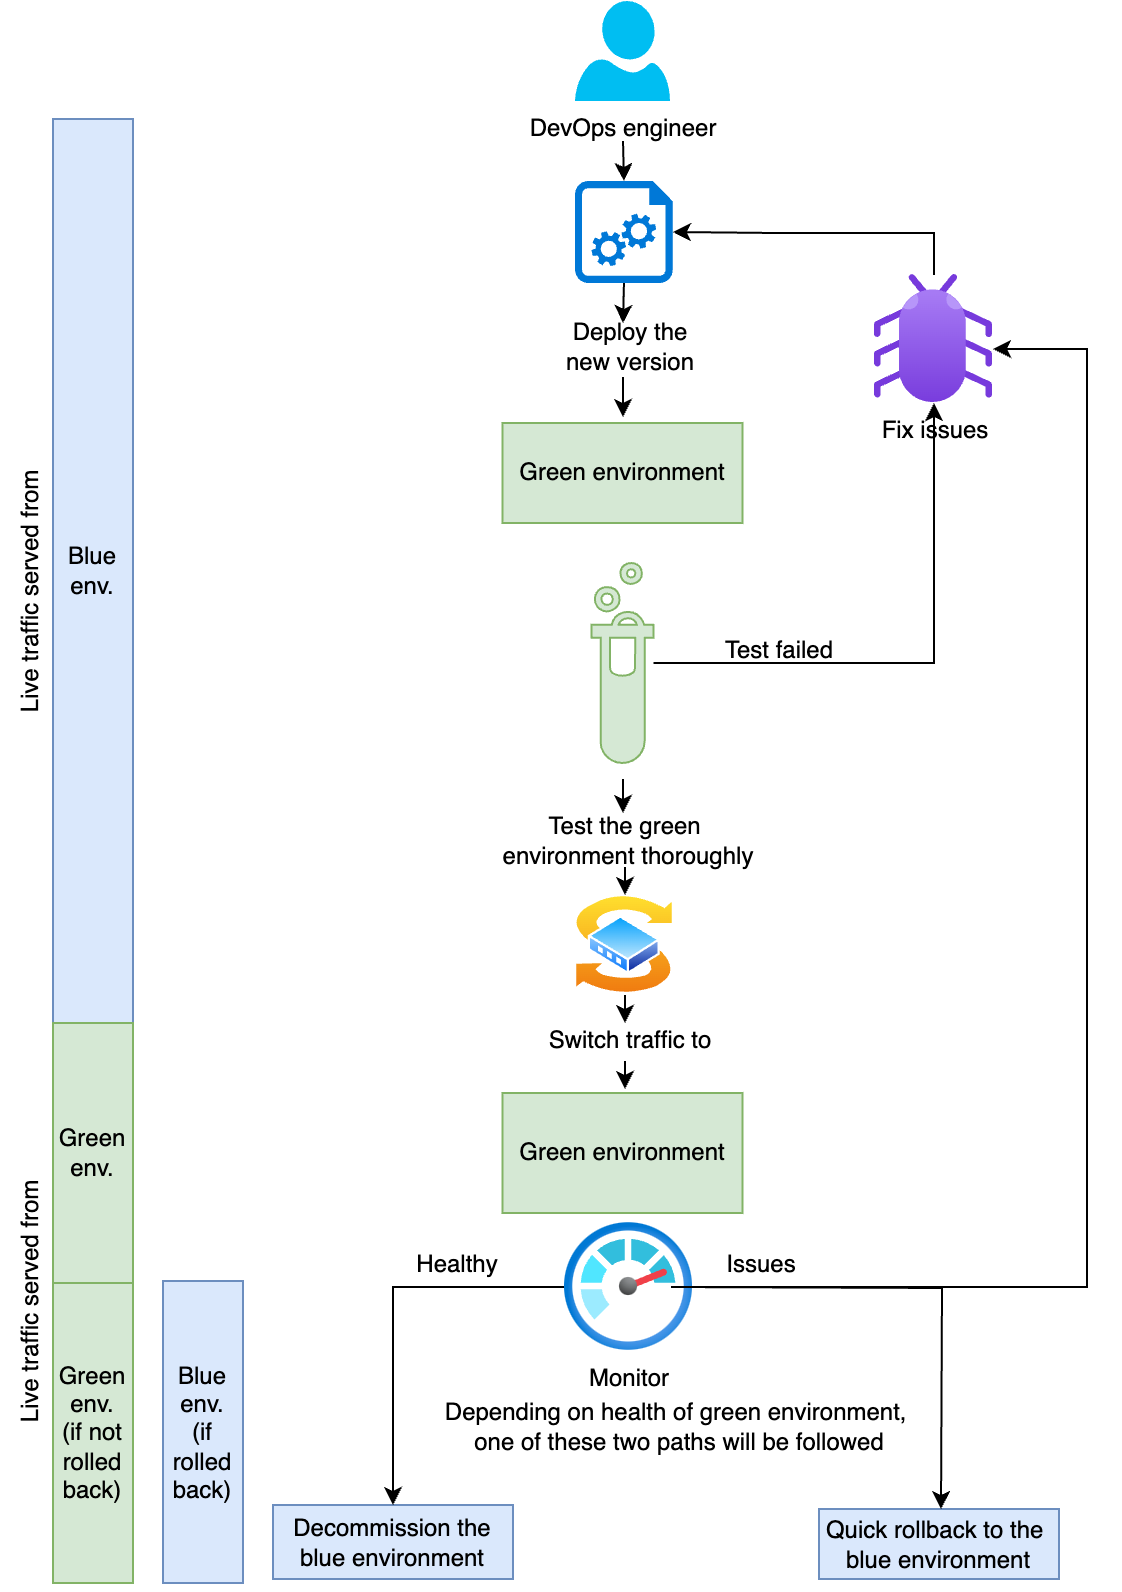
Modern applications require deployment strategies that minimize downtime and reduce risk. Blue/green deployment is a strategy that reduces downtime and risk by running two identical production environments called “blue” and “green”. At any given time, only one environment serves live production traffic while the other remains idle. This strategy provides immediate fallback to the previous stable version if issues arise after the new deployment. Let’s say a company is deploying a new version of its application. The following diagram shows the blue/green deployment strategy they are using.

Complete blue/green deployment strategy, including testing, monitoring, and conditional rollback procedures

As shown in the preceding diagram, current production traffic is served by the blue environment. During deployment of the new version of the application, the following sequence of activities happens:

  1. Deploy the new version of the application: Deploy the new version to the green environment.
  2. Test thoroughly: Test the new version in the green environment by invoking the API invoke URL from API Gateway. This does not affect production traffic, which continues to be served by the blue environment.
  3. Switch traffic: After you have thoroughly tested the green environment, redirect all production traffic from the blue to the green environment.
  4. Monitor and take any necessary action: Continue to monitor the green environment as it serves production traffic. Keep the blue environment ready for immediate rollback to the previous stable version, in case any issues arise in the green environment. At this point, one of two possible outcomes happens:
    1. If you identify any issues with the green environment in production, roll back to the previous stable version of the blue environment and fix the green environment before retrying.
    2. If you observe no issues with the green environment, decommission the blue environment. The green environment is now the new blue environment, the environment with stable production version of the application serving live traffic.

In this post, you learn how to implement blue/green deployments by using Amazon API Gateway for your APIs. For this post, we use AWS Lambda functions on the backend. However, you can follow the same strategy for other backend implementations of the APIs. All the required infrastructure is deployed by using AWS Serverless Application Model (AWS SAM).

Solution overview

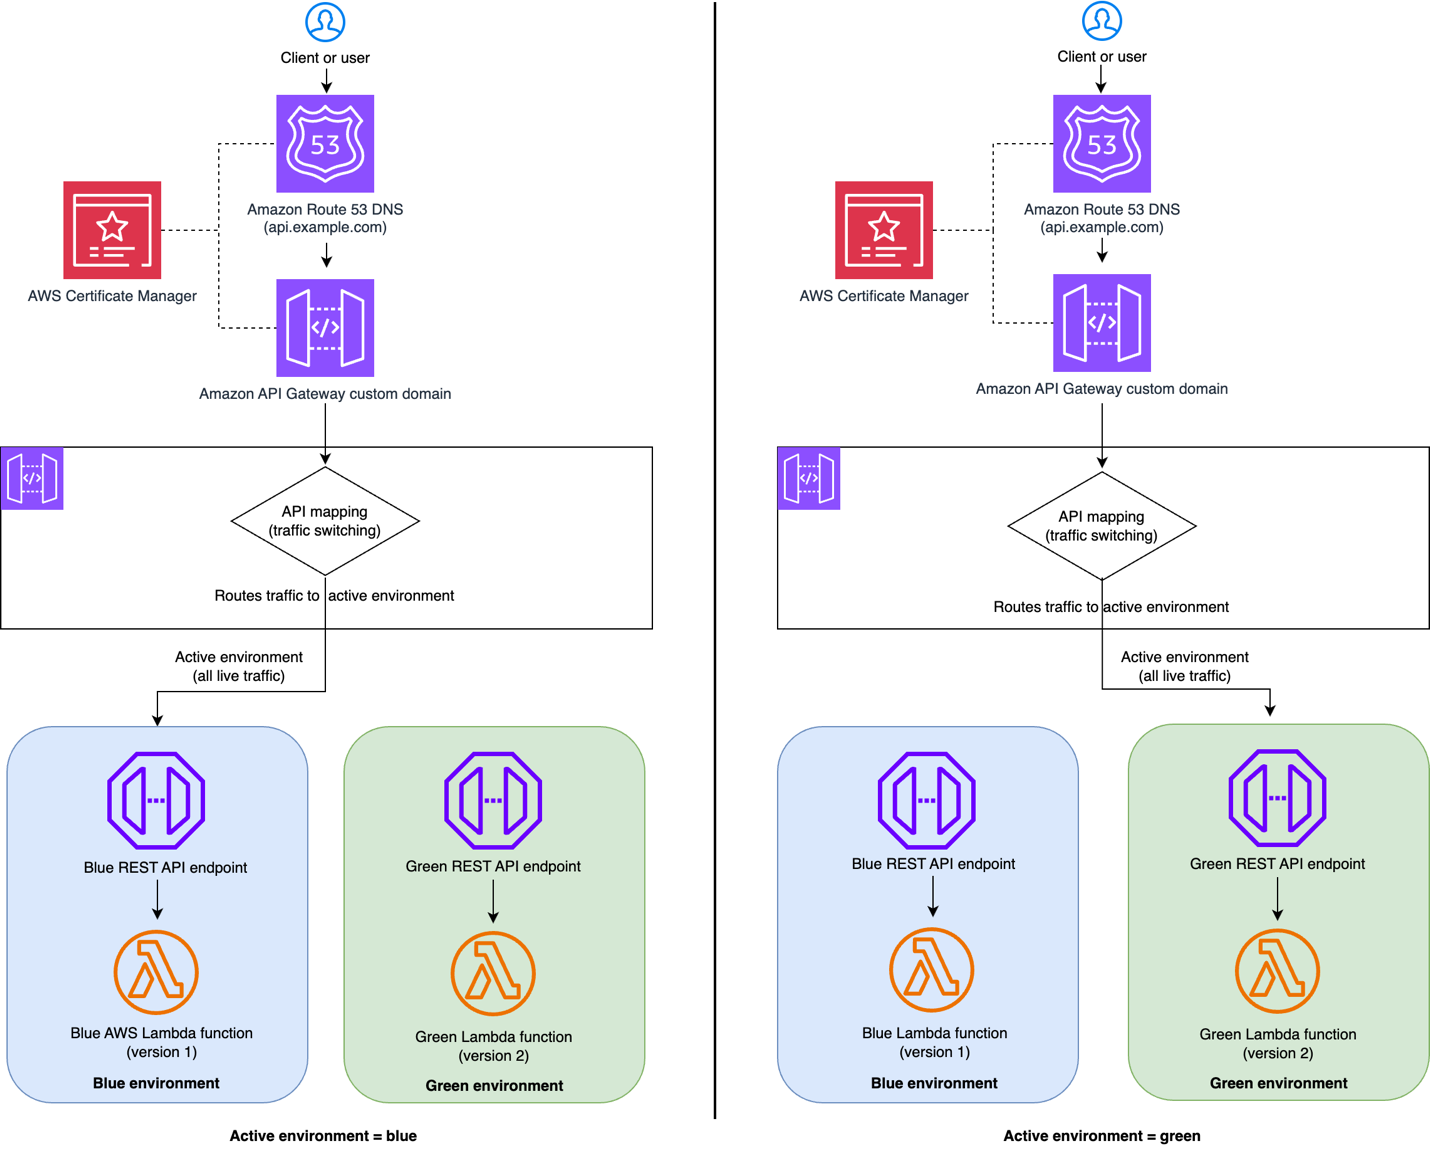
As you follow along with this post, you will implement the following blue/green deployment architecture by using API Gateway custom domain API mapping. You use API mappings to connect API stages to a custom domain name. After you create a domain name and configure DNS records, you use API mappings to send traffic to your APIs through your custom domain name.

AWS serverless architecture showing blue /green deployment using Amazon API Gateway custom domain

As shown in the preceding diagram, the blue/green deployment architecture includes four primary AWS services – Amazon Route 53, Amazon API Gateway, AWS Lambda functions, and AWS Certificate Manager (ACM). When you send a request to the API, the Route 53 resolves the domain to the API Gateway custom domain. API Gateway handles HTTPS termination by using a configured ACM certificate. API Gateway examines the incoming request path and headers to route the request to the active environment.

You first set up the blue environment along with the Route 53 DNS configuration, API Gateway custom domain mapping, ACM and test it with Route 53 URL. This is your production environment serving live traffic. After that, deploy a new version of the application in the green environment and test it by invoking the API invoke URL from API Gateway while live traffic is still being served from the blue environment. Then, switch the traffic from the blue environment to the green environment by using API Gateway custom domain API mapping. This ensures that there is no change in the external (client-facing) API custom domain URL. Live traffic is now served by the green environment. If you observe any issues during this time, you can quickly roll back to the blue environment and fix the green environment. If the green environment is stable, you can decommission the blue environment.

This post uses two separate regional API endpoints to simulate blue/green environments and traffic routing between them but you can this same architectural pattern using single API endpoint with two stages representing blue and green environments.

Prerequisites

Complete the following prerequisites before you start setting up the solution:

Set up and test the solution

Note that this is a sample project to understand the concept and not for direct usage in production. The sample project contains three APIs.

  • Health GET API to know the current health of the environment and which environment the request was served from.
  • Pets GET API to get the list of available pets.
  • Order POST API to place a pet order.

Follow the steps below to setup blue/green deployment and test it.

  1. Clone the repository and navigate to the directory (all commands run from here)
    Clone the GitHub repository in a new folder and navigate to the stacks folder.

    git clone https://github.com/aws-samples/sample-blue-green-deployment-with-api-gateway.git
    cd sample-blue-green-deployment-with-api-gateway/stacks

  2. Deploy the blue environment
    You will first setup the blue environment. Run the following commands to deploy the blue environment:

    sam build -t blue-stack.yaml
    sam deploy -g -t blue-stack.yaml

    Enter the following details:

    • Stack name: The CloudFormation stack name (for example, blue-green-api-blue)
    • AWS Region: A supported AWS Region (for example, us-east-1)
    • BlueLambdaFunction has no authentication. Is this okay?: y
    • SAM configuration file: blue-samconfig.toml

    Keep everything else set to their default values. You will use the SAM deploy output for the subsequent steps. Going forward, you can run the following command to deploy the blue environment resources:

    sam build -t blue-stack.yaml
    sam deploy -t blue-stack.yaml --config-file blue-samconfig.toml

  3. Test the blue environment

    Run the following commands to test the blue environment after replacing ApiEndpoint with BlueApiEndpoint from the SAM deploy output in each case. First, test Health check API to know the health of the environment. Run the following command.

    curl --request GET \ 
    --url https://<ApiEndpoint>/health

    Sample response:

    {
      "status": "healthy", 
      "environment": "blue", 
      "version": "v1.0.0", 
      "timestamp": "2025-09-05T13:11:11.248267Z"
    }

    Second, test the pets GET API request to get the list of available pets. Run the following command.

    curl --request GET \ 
    --url https://<ApiEndpoint>/pets

    Sample response:

    {
      "environment": "blue",
      "version": "v1.0.0",
      "pets": [
        {
          "id": 1,
          "name": "Buddy",
          "category": "dog",
          "status": "available"
        },
        {
          "id": 2,
          "name": "Whiskers",
          "category": "cat",
          "status": "available"
        },
        {
          "id": 3,
          "name": "Charlie",
          "category": "bird",
          "status": "pending"
        }
      ]
    }

    Now, test create order POST API to place an order for a pet:

    curl --request POST \
      --url https://<ApiEndpoint>/orders \
      --header 'content-type: application/json' \
      --data '{
      "id": 1,
      "name": "Buddy"
    }'

    Expected response:

    {
      "confirmationNumber": "ORD-3251C0F4", 
      "environment": "blue",
      "version": "v1.0.0",
      "timestamp": "2025-09-05T13:16:04.703666Z", 
      "data": 
      {
        "id": 1, 
        "name": "Buddy", 
        "status": "ordered"
      }
    }
    

    Check that the response contains the environment attribute set to blue and the version attribute set to v1.0.0

  4. Deploy API Gateway custom domain pointing to the blue environment

    Run the following commands to deploy Amazon API Gateway custom domain with API mapping pointing to the blue environment created in the previous step.

    sam build -t custom-domain-stack.yaml
    sam deploy -g -t custom-domain-stack.yaml

    Enter the following details:

    • Stack name: (for example, blue-green-api-custom-domain)
    • AWS Region: A supported AWS Region (for example, us-east-1)
    • PublicHostedZoneId: The Route 53 public hosted zone ID (for example, ABXXXXXXXXXXXXXXXXXYZ)
    • CustomDomainName: The Route 53 domain name (for example, api.example.com)
    • CertificateArn: The ACM certificate ARN (for example, arn:aws:acm:us-east-1:123456789012:certificate/abc123)
    • ActiveApiId: The value of the BlueApiId output from the blue-stack deployment
    • ActiveApiStage: The value of the BlueApiStage output from the blue-stack deployment
    • SAM configuration file: custom-domain-samconfig.toml

    Keep everything else to their default values. You will use the SAM deploy output for the subsequent steps. At this point the production (live) traffic is routed to blue environment.

  5. Test the production (live) traffic which is routed to blue environment

    Follow the test method mentioned in step 3 to test the production environment, but replace ApiEndpoint with CustomDomainUrl. Check that the production environment response contains the environment attribute set to blue and the version attribute set to v1.0.0

  6. Deploy the green environment

    You will now deploy the v2.0.0 of the application on green environment. Run the following commands to deploy the green environment:

    sam build -t green-stack.yaml
    sam deploy -g -t green-stack.yaml

    Enter the following details:

    • Stack name: (for example, blue-green-api-green)
    • AWS Region: Select the same Region as the blue environment (for example, us-east-1)
    • GreenLambdaFunction has no authentication. Is this okay?: y
    • SAM configuration file: green-samconfig.toml

    Keep everything else to default values. You will use the SAM deploy output for the subsequent steps. Going forward, you can run the following commands to deploy the green environment.

    sam build -t green-stack.yaml
    sam deploy -t green-stack.yaml --config-file green-samconfig.toml
    

  7. Test the green environment
    Follow the test method shown in step 3 to test the production environment, but replace ApiEndpoint with GreenApiEndpoint. Validate that the response contains the environment attribute set to green and the version attribute set to v2.0.0
  8. Switch the live traffic to the green environment
    Run the following command to switch live traffic to the green environment:

    sam deploy -g -t custom-domain-stack.yaml  --config-file custom-domain-samconfig.toml

    Enter the following details:

    • Stack name: Keep it as it is.
    • AWS Region: Keep it as it is.
    • PublicHostedZoneId: Keep it as it is.
    • CustomDomainName: Keep it as it is.
    • CertificateArn: Keep it as it is.
    • ActiveApiId: The value of GreenApiEndpoint output from the green-stack deployment
    • ActiveApiStage: The value of GreenApiStage output from the green-stack deployment
    • SAM configuration file: Keep it as it is.

    Keep everything else at their default values.

  9. Test the production environment (now green) again

    Follow the test method shown in step 3 to test the production environment (now green) again, and be sure to replace ApiEndpoint with CustomDomainUrl from SAM deploy output. Validate that the response now contains the environment attribute set to green and the version attribute set to v2.0.0. Note that it may take a minute or two for the change to be seen due to local DNS caching, during this time some of the traffic may be still served from the blue environment. After switching the live traffic to the green environment, if there is an issue, you can switch the live traffic back to the blue environment and fix the green environment. Depending on whether you need to roll back to the previous stable blue environment or decommission the blue environment when you no longer need it, follow either step 10 or 11.

  10. (Option 1) Roll back to the blue environment, if necessary
    Run the following command to roll back to the blue environment, if necessary.

    sam deploy -g -t custom-domain-stack.yaml  --config-file custom-domain-samconfig.toml

    Enter the following details:

    • Stack name: Keep it as it is.
    • AWS Region: Keep it as it is.
    • PublicHostedZoneId: Keep it as it is.
    • CustomDomainName: Keep it as it is.
    • CertificateArn: Keep it as it is.
    • ActiveApiId: Value of BlueApiEndpoint output from the blue-stack deployment.
    • ActiveApiStage: The value of BlueApiStage output from the blue-stack deployment.
    • SAM configuration file: Keep it as it is.

    Keep everything else to their default values. Live traffic is switched to the blue environment. You can confirm that by following step 3.

  11. (Option 2) Decommission the blue environment when you no longer need it
    Run the following command to decommission (delete) the blue environment when you no longer need it. Replace blue-stack-name with your blue deployment stack name:

    sam delete --stack-name <blue-stack-name> --no-prompts

Clean up

To avoid costs, remove all resources created along this post once you’re done.

Run the following command after replacing the <placeholder> variables to delete the resources you deployed for this post’s solution:

# Delete all stacks (in reverse order)
# Delete custom domain
sam delete --stack-name <api-custom-domain-stack-name> --no-prompts
# Delete green stack
sam delete --stack-name <green-stack-name> --no-prompts
# Delete blue stack, if already not deleted in step 10
sam delete --stack-name <blue-stack-name> --no-prompts

Conclusion

Blue/green deployments with API Gateway provide a robust, scalable solution for zero-downtime deployments that deliver significant technical and operational advantages. This post’s solution architecture enables traffic switching at the API Gateway level while maintaining complete isolation between the blue and green environments to prevent interference. The solution offers immediate rollback capabilities for quick issue resolution and supports comprehensive testing through production-like validation before any traffic switching occurs.

Following this solution you can build a solid foundation for production blue/green deployments for your serverless microservice architecture that maintains the flexibility to adapt to your specific requirements while ensuring reliability, scalability, and operational excellence. To learn more about serverless architectures see Serverless Land.

Stream mainframe data to AWS in near real time with Precisely and Amazon MSK

Post Syndicated from Supreet Padhi original https://aws.amazon.com/blogs/big-data/stream-mainframe-data-to-aws-in-near-real-time-with-precisely-and-amazon-msk/

This is a guest post by Supreet Padhi, Technology Architect, and Manasa Ramesh, Technology Architect at Precisely in partnership with AWS.

Enterprises rely on mainframes to run mission-critical applications and store essential data, enabling real-time operations that help achieve business objectives. These organizations face a common challenge: how to unlock the value of their mainframe data in today’s cloud-first world while maintaining system stability and data quality. Modernizing these systems is critical for competitiveness and innovation.

The digital transformation imperative has made mainframe data integration with cloud services a strategic priority for enterprises worldwide. Organizations that can seamlessly bridge their mainframe environments with modern cloud platforms gain significant competitive advantages through improved agility, reduced operational costs, and enhanced analytics capabilities. However, implementing such integrations presents unique technical challenges that require specialized solutions. Some of the challenges include converting EBCDIC data to ASCII, where the handling of data types is unique to the mainframe, such as binary data and COMP data. Data stored in Virtual Storage Access Method (VSAM) files can be quite complex due to practices to store multiple different record types in a single file. To address these challenges, Precisely—a global leader in data integrity, serving over 12,000 customers—has partnered with Amazon Web Services (AWS) to enable real-time synchronization between mainframe systems and Amazon Relational Database Service (Amazon RDS). For more on this collaboration, check out our previous blog post: Unlock Mainframe Data with Precisely Connect and Amazon Aurora.

In this post, we introduce an alternative architecture to synchronize mainframe data to the cloud using Amazon Managed Streaming for Apache Kafka (Amazon MSK) for greater flexibility and scalability. This event-driven approach provides additional possibilities for mainframe data integration and modernization strategies.

A key enhancement in this solution is the use of the AWS Mainframe Modernization – Data Replication for IBM z/OS Amazon Machine Image (AMI) available in AWS Marketplace, which simplifies deployment and reduces implementation time.

Real-time processing and event-driven architecture benefits

Real-time processing makes data actionable within seconds rather than waiting for batch processing cycles. For example, financial institutions such as Global Payments have leveraged this solution to modernize mission-critical banking operations, including payments processing. By migrating these operations to the AWS Cloud, they enhanced user experience, improved scalability and maintainability, while enabling advanced fraud detection – all without impacting the performance of existing mainframe systems. Change data capture (CDC) enables this by identifying database changes and delivering them in real time to cloud environments.

CDC offers two key advantages for mainframe modernization:

  • Incremental data movement – Eliminates disruptive bulk extracts by streaming only changed data to cloud targets, minimizing system impact and ensuring data currency
  • Real-time synchronization – Keeps cloud applications in sync with mainframe systems, enabling immediate insights and responsive operations

Solution overview

In this post, we provide a detailed implementation guide for streaming mainframe data changes from DB2z through AWS Mainframe Modernization – Data Replication for IBM z/OS AMI to Amazon MSK and then applying those changes to Amazon Relational Database Service (Amazon RDS) for PostgreSQL using MSK Connect with the Confluent JDBC Sink Connector.

By introducing Amazon MSK into architecture and streamlining deployment through the AWS Marketplace AMI, we create new possibilities for data distribution, transformation, and consumption that expand upon our previously demonstrated direct replication approach. This streaming-based architecture offers several additional benefits:

  • Simplified deployment – Accelerate implementation using the preconfigured AWS Marketplace AMI
  • Decoupled systems – Separate the concern of data extraction from data consumption, allowing both sides to scale independently
  • Multi-consumer support – Enable multiple downstream applications and services to consume the same data stream according to their own requirements
  • Extensibility – Create a foundation that can be extended to support additional mainframe data sources such as IMS and VSAM, as well as additional AWS targets using MSK Connect sink connectors

The following diagram illustrates the solution architecture.

Precisely MSK architecture diagram

  1. Capture/Publisher – Connect CDC Capture/Publisher captures Db2 changes from Db2 logs using IFI 306 Read and communicates captured data changes to a target engine through TCP/IP.
  2. Controller Daemon – The Controller Daemon authenticates all connection requests, managing secure communication between the source and target environments.
  3. Apply Engine – The Apply Engine is a multifaceted and multifunctional component in the target environment. It receives the changes from the Publisher agent and applies the changed data to the target Amazon MSK.
  4. Connect CDC Single Message Transform (SMT) – Performs all necessary data filtering, transformation, and augmentation required by the sink connector.
  5. JDBC Sink Connector – As data arrives, an instance of the JDBC Sink Connector along with Apache Kafka writes the data to target tables in Amazon RDS.

This architecture provides a clean separation between the data capture process and the data consumption process, allowing each to scale independently. The use of MSK as an intermediary enables multiple systems to consume the same data stream, opening possibilities for complex event processing, real-time analytics, and integration with other AWS services.

Prerequisites

To complete the solution, you need the following prerequisites:

  1. Install AWS Mainframe Modernization – Data Replication for IBM z/OS
  2. Have access to Db2z on mainframe from AWS using your approved connectivity between AWS and your mainframe

Solution walkthrough

The following code content shouldn’t be deployed to production environments without additional security testing.

Configure the AWS Mainframe Modernization Data Replication with Precisely AMI on Amazon EC2

Follow the steps defined at Precisely AWS Mainframe Modernization Data Replication. Upon the initial launch of the AMI, use the following command to connect to the Amazon Elastic Compute Cloud (Amazon EC2) instance:

ssh -i ami-ec2-user.pem ec2-user@$AWS_AMI_HOST

Configure the serverless cluster

To create an Amazon Aurora PostgreSQL-Compatible Edition Serverless v2 cluster, complete the following steps:

  1. Create a DB cluster by using the following AWS Command Line Interface (AWS CLI) command. Replace the placeholder strings with values that correspond to your cluster’s subnet and subnet group IDs.
    aws rds create-db-cluster \
       --db-cluster-identifier cdc-serverless-pg-cluster \
       --engine aurora-postgresql \
       --serverless-v2-scaling-configuration MinCapacity=1,MaxCapacity=2 \
       --master-username connectcdcuser \
       --manage-master-user-password \
       --db-subnet-group-name "<subnet-security-group-id>" \
       --vpc-security-group-ids "<cluster-security-group-id>"

  2. Verify the status of the cluster by using the following command:
    aws rds describe-db-clusters --db-cluster-identifier cdc-serverless-pg-cluster

  3. Add a writer DB instance to the Aurora cluster:
    aws rds create-db-instance \
       --db-cluster-identifier cdc-serverless-pg-cluster \
       --db-instance-identifier cdc-serverless-pg-instance \
       --db-instance-class db.serverless \
       --engine aurora-postgresql

  4. Verify the status of the writer instance:
    aws rds describe-db-instances --db-instance-identifier cdc-serverless-pg-instance

Create a database in the PostgreSQL cluster

After your Aurora Serverless v2 cluster is running, you need to create a database for your replicated mainframe data. Follow these steps:

  1. Install the psql client:
    sudo yum install postgresql16

  2. Retrieve the password from secret manager:
    aws secretsmanager get-secret-value --secret-id '<cdc-serverless-pg-cluster-secret ARN>' --query 'SecretString' --output text

  3. Create a new database in PostgreSQL:
    PGPASSWORD="password" psql --host=<DATABASE-HOST> --username=connectcdcuser --dbname=postgres -c "CREATE DATABASE dbcdc"

Configure the serverless MSK cluster

To create a serverless MSK cluster, complete the following steps:

  1. Copy the following JSON and paste it into a new file create-msk-serverless-cluster.json. Replace the placeholder strings with values that correspond to your cluster’s subnet and security group IDs.
       {
         "VpcConfigs": [
           {
             "subnets": [
               "<cluster-subnet-1>",
               "<cluster-subnet-2>",
               "<cluster-subnet-3>"
             ],
             "securityGroups": ["<cluster-security-group-id>"]
           }
         ],
         "ClientAuthentication": {
           "Sasl": {
             "Iam": {
               "Enabled": true
             }
           }
         }
       }

  2. Invoke the following AWS CLI command in the folder where you saved the JSON file in the previous step:
    aws kafka create-cluster-v2 --cluster-name pgsqlmsk --serverless file://create-msk-serverless-cluster.json

  3. Verify cluster status by invoking the following AWS CLI command:
    aws kafka list-clusters-v2 --cluster-type-filter SERVERLESS

  4. Get the bootstrap broker address by invoking the following AWS CLI command:
    aws kafka get-bootstrap-brokers --cluster-arn "<msk-serverless-cluster-arn>"

  5. Define the environment variable to store the bootstrap servers of the MSK cluster and locally install Kafka in the path environment variable:
    export BOOTSTRAP_SERVERS=<kafka_bootstrap_servers_with_ports>

Create a topic on the MSK cluster

To create a Kafka topic, you need to install the Kafka CLI first. Follow these steps:

  1. Download the binary distribution of Apache Kafka and extract the archive in folder kafka:
    wget https://dlcdn.apache.org/kafka/3.9.0/kafka_2.13-3.9.0.tgz
       tar -xzf kafka_2.13-3.9.0.tgz
       ln -sfn kafka_2.13-3.9.0 kafka

  2. To use IAM to authenticate with the MSK cluster, download the Amazon MSK Library for IAM and copy to the local Kafka library directory as shown in the following code. For complete instructions, refer to Configure clients for IAM access control.
    wget https://github.com/aws/aws-msk-iam-auth/releases/download/v2.3.1/aws-msk-iam-auth-2.3.1-all.jar
    cp aws-msk-iam-auth-2.3.1-all.jar kafka/libs

  3. In the directory, create a file to configure a Kafka client to use IAM authentication for the Kafka console producer and consumers:
    security.protocol=SASL_SSL
       sasl.mechanism=AWS_MSK_IAM
       sasl.jaas.config=software.amazon.msk.auth.iam.IAMLoginModule required; sasl.client.callback.handler.class=software.amazon.msk.auth.iam.IAMClientCallbackHandler

  4. Create the Kafka topic, which you defined in the connector config:
    kafka/bin/kafka-topics.sh --create --bootstrap-server $BOOTSTRAP_SERVERS --command-config kafka/config/client-config.properties --partitions 1 --topic pgsql-sink-topic

Configure the MSK Connect plugin

Next, create a custom plugin available in the AMI at /opt/precisely/di/packages/sqdata-msk_connect_1.0.1.zip which contains the following:

  • JDBC Sink Connector from Confluent
  • MSK Config provider
  • AWS Mainframe Modernization – Data Repication for IBM z/OS Custom SMT

Follow these steps:

  1. Invoke the following to upload the .zip file to an S3 bucket to which you have access:
    aws s3 cp /opt/precisely/di/packages/sqdata-msk_connect_1.0.1.zip s3://<bucket>/

  2. Copy the following JSON and paste it into a new file create-custom-plugin.json. Replace the placeholder strings with values that correspond to your bucket.
    {
         "contentType": "ZIP",
         "description": "jdbc sink connector",
         "location": {
           "s3Location": {
             "bucketArn": "arn:aws:s3:::<bucket>",
             "fileKey": "sqdata-msk_connect_1.0.1.zip"
           }
         },
         "name": "jdbc-sink-connector"
       }

  3. Invoke the following AWS CLI command in the folder where you saved the JSON file in the previous step:
    aws kafkaconnect create-custom-plugin --cli-input-json file://create-custom-plugin.json

  4. Verify plugin status by invoking the following AWS CLI command:
    aws kafkaconnect list-custom-plugins

Configure the JDBC Sink Connector

To configure the JDBC Sink Connector, follow these steps:

  1. Copy the following JSON and paste it into a new file create-connector.json. Replace the placeholder strings with appropriate values:
    {
         "connectorConfiguration": {
           "connector.class": "io.confluent.connect.jdbc.JdbcSinkConnector",
           "connection.url": "jdbc:postgresql://<postgresql-endpoint>
    /dbcdc?currentSchema=public",
           "config.providers": "secretsmanager",
           "config.providers.secretsmanager.class": "com.amazonaws.kafka.config.providers.SecretsManagerConfigProvider",
           "connection.user": "${secretsmanager:MySecret-1234:username}",
           "connection.password": "${secretsmanager:MySecret-1234:password}",
           "config.providers.secretsmanager.param.region": "<region>",
           "tasks.max": "1",
           "topics": "pgsql-sink-topic",
           "insert.mode": "upsert",
           "delete.enabled": "true",
           "pk.mode": "record_key",
           "auto.evolve": "true",
           "auto.create": "true",
           "value.converter": "org.apache.kafka.connect.storage.StringConverter",
           "key.converter": "org.apache.kafka.connect.storage.StringConverter",
           "transforms": "ConnectCDCConverter",
           "transforms.ConnectCDCConverter.type": "com.precisely.kafkaconnect.ConnectCDCConverter",
           "transforms.ConnectCDCConverter.cdc.multiple.tables.enabled": "true",
           "transforms.ConnectCDCConverter.cdc.source.table.name.ignore.schema": "true"
         },
         "connectorName": "pssql-sink-connector",
         "kafkaCluster": {
           "apacheKafkaCluster": {
             "bootstrapServers": "<msk-bootstrap-servers-string>",
             "vpc": {
               "subnets": [
                 "<cluster-subnet-1>",
                 "<cluster-subnet-2>",
                 "<cluster-subnet-3>"
               ],
               "securityGroups": ["<cluster-security-group-id>"]
             }
           }
         },
         "capacity": {
           "provisionedCapacity": {
             "mcuCount": 1,
             "workerCount": 1
           }
         },
         "kafkaConnectVersion": "3.7.x",
         "serviceExecutionRoleArn": "<arn-of-a-role-that-msk-connect-can-assume>",
         "plugins": [
           {
             "customPlugin": {
               "customPluginArn": "<arn-of-custom-plugin-that-contains-connector-code>",
               "revision": 1
             }
           }
         ],
         "kafkaClusterEncryptionInTransit": {"encryptionType": "TLS"},
         "kafkaClusterClientAuthentication": {"authenticationType": "IAM"},
         "logDelivery": {
           "workerLogDelivery": {
             "cloudWatchLogs": {
               "enabled": true,
               "logGroup": "<loggroup>"
             }
           }
         }
       }

  2. Invoke the following AWS CLI command in the folder where you saved the JSON file in the previous step:
    aws kafkaconnect create-connector --cli-input-json file://create-connector.json

  3. Verify connector status by invoking the following AWS CLI command:
    aws kafkaconnect list-connectors

Set up Db2 Capture/Publisher on Mainframe

To establish the Db2 Capture/Publisher on the mainframe for capturing changes to the DEPT table, follow these structured steps that build upon our previous blog post, Unlock Mainframe Data with Precisely Connect and Amazon Aurora:

  1. Prepare the source table. Before configuring the Capture/Publisher, ensure the DEPT source table exists on your mainframe Db2 system. The table definition should match the structure defined at \$SQDATA_VAR_DIR/templates/dept.ddl. If you need to create this table on your mainframe, use the DDL from this file as a reference to ensure compatibility with the replication process.
  2. Access the Interactive System Productivity Facility (ISPF) interface. Sign in to your mainframe system and access the AWS Mainframe Modernization – Data Repication for IBM z/OS ISPF panels through the supplied ISPF application menu. Select option 3 (CDC) to access the CDC configuration panels, as demonstrated in our previous blog post.
  3. Add source tables for capture:
    1. From the CDC Primary Option Menu, choose option 2 (Define Subscriptions).
    2. Choose option 1 (Define Db2 Tables) to add source tables.
    3. On the (Add DB2 Source Table to CAB File panel), enter a wildcard value (%) or the specific table name DEPT in the (Table Name) field.
    4. Press Enter to display the list of available tables.
    5. Type S next to the DEPT table to select it for replication, then press Enter to confirm.

This process is like the table selection process shown in figure 3 and figure 4 of our previous post but now focuses specifically on the DEPT table structure.

With the completion of both the Db2 Capture/Publisher setup on the mainframe and the AWS environment configuration (Amazon MSK, Apply Engine, and MSK Connect JDBC Sink Connector), you now have a fully functional pipeline ready to capture data changes from the mainframe and stream them to the MSK topic. Inserts, updates, or deletions to the DEPT table on the mainframe will be automatically captured and pushed to the MSK topic in near real time. From there, the MSK Connect JDBC Sink Connector and the custom SMT will process these messages and apply the changes to the PostgreSQL database on Amazon RDS, completing the end-to-end replication flow.

Configure Apply Engine for Amazon MSK integration

Configure the AWS side components to receive data from the mainframe and forward it to Amazon MSK. Follow these steps to define and manage a new CDC pipeline from DB2 z/OS to Amazon MSK:

  1. Use the following command to switch to the connect user:
    sudo su connect

  2. Create the apply engine directories:
    mkdir -p \$SQDATA_VAR_DIR/apply/DB2ZTOMSK/ddl
         connect> mkdir -p \$SQDATA_VAR_DIR/apply/DB2ZTOMSK/scripts

  3. Copy the sample script from dept.ddl:
    cp \$SQDATA_VAR_DIR/templates/dept.ddl \$SQDATA_VAR_DIR/apply/DB2ZTOMSK/ddl/

  4. Copy the following content and paste it in a new file $SQDATA_VAR_DIR/apply/DB2ZTOMSK/scripts/DB2ZTOMSK.sqd. Replace the placeholder strings with values that correspond to the DB2z endpoint:
    -----------------------------------------------------------------------
       Name: DB2TOKAF: Z/OS DB2 To Kafka
       -----------------------------------------------------------------------
       SUBSTITUTION PARMS USED IN THIS SCRIPT:
       ---------------------------------------------------------------------
       JOBNAME DB2TOKAFKA;
       -----------------------------
       TABLE DESCRIPTIONS
       ---------------------------
       BEGIN GROUP SOURCE_TABLES;
       DESCRIPTION Db2SQL /var/precisely/di/sqdata/apply/DB2ZTOMSK/ddl/dept.ddl AS DEPT KEY IS DEPTNO;
       END GROUP;
       -------------------------------------------------------------
       DATASTORE SECTION
       -------------------------------------------------------------
       SOURCE DATASTORE
       DATASTORE cdc://<DB2z endpoint with port>/dbcg/DBCG_TBTSS388T6 OF UTSCDC AS CDCIN DESCRIBED BY GROUP SOURCE_TABLES;
       -- TARGET DATASTORE
       DATASTORE kafka:///pgsql-sink-topic/table_key OF JSON AS TARGET KEY IS DEPTNO DESCRIBED BY GROUP SOURCE_TABLES;
       ---------------------------------
       PROCESS INTO TARGET
       SELECT { REPLICATE(TARGET) } FROM CDCIN;

  5. Create the working directory:
    mkdir -p /var/precisely/di/sqdata_logs/apply/DB2ZTOMSK

  6. Add the following to $SQDATA_DAEMON_DIR/cfg/sqdagents.cfg:
    [DB2ZTOMSK]
       type=engine
       program=sqdata
       args=/var/precisely/di/sqdata/apply/DB2ZTOMSK/scripts/DB2ZTOMSK.prc --log-level=8
       working_directory=/var/precisely/di/sqdata_logs/apply/DB2ZTOMSK
       stdout_file=stdout.txt
       stderr_file=stderr.txt
       auto_start=0
       comment=Apply Engine for MSK from Db2z

  7. After the preceding code is added to the sqdagents.cfg section, reload for the changes to take effect:
    sqdmon reload

  8. Validate the apply engine job script by using the SQData parse command to create the compiled file expected by the SQData engine:
    sqdparse $SQDATA_VAR_DIR/apply/DB2ZTOMSK/scripts/DB2ZTOMSK.sqd $SQDATA_VAR_DIR/apply/DB2ZTOMSK/scripts/DB2ZTOMSK.prc

    The following is an example of the output that you get when you invoke the command successfully:

    SQDC042I mounting/running sqdparse with arguments:
    SQDC041I args[0]:sqdparse
    SQDC041I args[1]:/var/precisely/di/sqdata/apply/DB2ZTOMSK/scripts/DB2ZTOMSK.sqd
    SQDC041I args[2]:/var/precisely/di/sqdata/apply/DB2ZTOMSK/scripts/DB2ZTOMSK.prc
    SQDC000I *******************************************************
    SQDC021I sqdparse Version 5.0.1-rel (Linux-x86_64)
    SQDC022I Build-id 4f2d7c16728aa2e40c610db7d5a6e373476a9889
    SQDC023I (c) 2001, 2025 Syncsort Incorporated. All rights reserved.
    SQDC000I *******************************************************
    SQDC000I
    SQD0000I 2025-03-31 00:59:10
    >>> Start Preprocessed /var/precisely/di/sqdata/apply/DB2ZTOMSK/scripts/DB2ZTOMSK.sqd
    000001 ----------------------------------------------------------------------
    000002 -- Name: DB2TOKAF:  Z/OS DB2 To Kafka
    000003 ----------------------------------------------------------------------
    000004 --  SUBSTITUTION PARMS USED IN THIS SCRIPT:
    000005 ----------------------------------------------------------------------
    000006
    000007 JOBNAME DB2TOKAFKA;
    000008
    000009 ----------------------------
    000010 -- TABLE DESCRIPTIONS
    000011 ----------------------------
    000012 BEGIN GROUP SOURCE_TABLES;
    000013 DESCRIPTION Db2SQL /var/precisely/di/sqdata/apply/DB2ZTOMSK/ddl/dept.ddl  AS DEPT
    000014 KEY IS DEPTNO;
    000015 END GROUP;
    000016
    000017 ------------------------------------------------------------
    000018 --       DATASTORE SECTION
    000019 ------------------------------------------------------------
    000020
    000021 -- SOURCE DATASTORE
    000022 DATASTORE /var/precisely/di/sqdata/apply/DB2ZTOMSK/scripts/DB0A.ENGINE3.DEPT.COPY
    000023           OF UTSCDC
    000024           AS CDCIN
    000025           DESCRIBED BY GROUP SOURCE_TABLES;
    000026
    000027 -- TARGET DATASTORE
    000028 DATASTORE 
    000029           OF JSON
    000030           AS TARGET
    000031           KEY IS DEPTNO
    000032           DESCRIBED BY GROUP SOURCE_TABLES;
    000033
    000034 ----------------------------------
    000035
    000036 PROCESS INTO TARGET
    000037 SELECT
    000038 {
    000039     REPLICATE(TARGET)
    000040 }
    000041 FROM CDCIN;
    <<< End Preprocessed /var/precisely/di/sqdata/apply/DB2ZTOMSK/scripts/DB2ZTOMSK.sqd
    >>> Start Preprocessed /var/precisely/di/sqdata/apply/DB2ZTOMSK/ddl/dept.ddl
    000001 CREATE TABLE DEPARTMENT
    000002 (
    000003    DEPTNO char(3) NOT NULL,
    000004    DEPTNAME varchar(36) NOT NULL,
    000005    MGRNO char(6),
    000006    ADMRDEPT char(3) NOT NULL,
    000007    LOCATION char(16),
    000008    CONSTRAINT PK_DEPTNO PRIMARY KEY (DEPTNO)
    000009 ) ;
    <<< End Preprocessed /var/precisely/di/sqdata/apply/DB2ZTOMSK/ddl/dept.ddl
    Number of Data Stores...................: 2
    Data Store..............................: /var/precisely/di/sqdata/apply/DB2ZTOMSK/scripts/DB0A.ENGINE3.DEPT.COPY
      Alias.................................: CDCIN
      Type..................................: UTS Change Data Capture
      Number of Records.....................: 1
        Record Name.........................: DEPARTMENT
        Record Description Alias............: DEPT
        Record Description Length...........: 72
        Number of Fields....................: 5
          ................................... TYPE            OFF   LEN   XLEN  EXT
          ................................... ---------- ----- ----- ----- -----
          DEPTNO............................: CHAR(3)             0     3     3
          DEPTNAME..........................: VARCHAR(36)         3    38    38
          MGRNO.............................: CHAR(6)             7     6     6
          ADMRDEPT..........................: CHAR(3)            14     3     3
          LOCATION..........................: CHAR(16)           17    16    16
    Data Store..............................: 
      Alias.................................: TARGET
      Type..................................: JSON
      Number of Records.....................: 1
        Record Name.........................: DEPARTMENT
        Record Description Alias............: DEPT
        Record Description Length...........: 70
        Number of Fields....................: 5
          ................................... TYPE            OFF   LEN   XLEN  EXT
          ................................... ---------- ----- ----- ----- -----
          DEPTNO............................: CHAR(3)             0     3     3
          DEPTNAME..........................: VARCHAR(36)         3    38    38
          MGRNO.............................: CHAR(6)            41     6     6
          ADMRDEPT..........................: CHAR(3)            47     3     3
          LOCATION..........................: CHAR(16)           50    16    16
    Section.................................: SQDSTP000
      Number of steps.......................: 1
    SQDC017I sqdparse(pid=4023) terminated successfully

  9. Copy the following content and paste it in a new file /var/precisely/di/sqdata_logs/apply/DB2ZTOMSK/sqdata_kafka_producer.conf. Replace the placeholder strings with values that correspond to your bootstrap server and AWS Region.
    metadata.broker.list=<kafka_bootstrap_servers_with_ports>
         security.protocol=SASL_SSL
         sasl.mechanism=OAUTHBEARER
         sasl.oauthbearer.config="extension_AWSMSKCB=python3,/usr/lib64/python3.9/site-packages/aws_msk_iam_sasl_signer/cli.py,--region,<region>"
         sasl.oauthbearer.method="default"

  10. Start the apply engine using the controller daemon by using the following command:
    sqdmon start ///DB2ZTOMSK

  11. Monitor the apply engine through the controller daemon by using the following command:
    sqdmon display ///DB2ZTOMSK --format=details

    The following is an example of the output that you get when you invoke the command successfully:

    Engine..................................: DB2ZTOMSK
    version.................................: 5.0.1-rel (Linux-x86_64)
    git.....................................: f021c29a84c1a99f59144288aeeb2cb8fa494485
    jobname.................................: DB2TOKAFKA
    parsed..................................: 20250320172610278108
    started.................................: 2025-03-20.17.47.23.444474
    started (UTC)...........................: 2025-03-20.17.47.23.444474 (1742492843444)
    updated (UTC)...........................: 2025-03-20.17.47.25.901018 (1742492845901)
    Input Datastore.........................: /var/precisely/di/sqdata/apply/DB2ZTOMSK/scripts/DB0A.ENGINE3.DEPT.COPY
    Alias...................................: CDCIN
    Type....................................: UTS Change Data Capture
      Records Read..........................: 14
      Records Selected......................: 14
      Bytes Read............................: 2892
    Output Datastore........................: kafka:///pgsql-sink-topic/table_key
    Alias...................................: TARGET
    Type....................................: JSON
      Records Inserted......................: 14
      Records Updated.......................: 0
      Records Deleted.......................: 0
      Formatted bytes.......................: 3458
      Unformatted bytes.....................: 448
    Total Output Formatted bytes............: 3458
    Total Output Unformatted bytes..........: 448
    SQDC017I sqdmon(pid=123540) terminated successfully

    Logs can also be found at /var/precisely/di/sqdata_logs/apply/DB2ZTOMSK.

Verify data in the MSK topic

Invoke the Kafka CLI command to verify the JSON data in the MSK topic:

kafka/bin/kafka-console-consumer.sh --bootstrap-server $BOOTSTRAP_SERVERS --consumer.config kafka/config/client-config.properties --topic pgsql-sink-topic --from-beginning --property print.key=true

Verify data in the PostgreSQL database

Invoke the following command to verify the data in the PostgreSQL database:

PGPASSWORD="password" psql --host=<DATABASE-HOST> --username=<user> --dbname=<database> -c "select * from \"DEPT\""

With these steps completed, you’ve successfully set up end-to-end data replication from DB2z to RDS for PostgreSQL, using AWS Mainframe Modernization – Data Replication for IBM z/OS AMI, Amazon MSK, MSK Connect, and the Confluent JDBC Sink Connector.

Cleanup

When you’re finished testing this solution, you can clean up the resources to avoid incurring additional charges. Follow these steps in sequence to ensure proper cleanup.

Step 1: Delete the MSK Connect components

Follow these steps:

  1. List existing connectors:
    aws kafkaconnect list-connectors

  2. Delete the sink connector:
    aws kafkaconnect delete-connector --connector-arn "<arn-of-connector>"

  3. List custom plugins:
    aws kafkaconnect list-custom-plugins

  4. Delete the custom plugin:
    aws kafkaconnect delete-custom-plugin --custom-plugin-arn "<arn-of-custom-plugin>"

Step 2: Delete the MSK cluster

Follow these steps:

  1. List MSK clusters:
    aws kafka list-clusters-v2 --cluster-type-filter SERVERLESS

  2. Delete the MSK serverless cluster:
    aws kafka delete-cluster --cluster-arn "<arn-of-msk-serverless-cluster>"

Step 3: Delete the Aurora resources

Follow these steps:

  1. Delete the Aurora DB instance:
    aws rds delete-db-instance --db-instance-identifier cdc-serverless-pg-instance --skip-final-snapshot

  2. Delete the Aurora DB cluster:
    aws rds delete-db-cluster --db-cluster-identifier cdc-serverless-pg-cluster --skip-final-snapshot.

Conclusion

By capturing changed data from DB2z and streaming it to AWS targets, organizations can modernize their legacy mainframe data stores, enabling operational insights and AI initiatives. Businesses can use this solution to take advantage of cloud-based applications with mainframe data to provide scalability, cost-efficiency, and enhanced performance.

The integration of AWS Mainframe Modernization – Data Replication for IBM z/OS AMI with Amazon MSK and RDS for PostgreSQL provides an enhanced framework for real-time data synchronization that maintains data integrity. This architecture can be extended to support additional mainframe data sources such as VSAM and IMS, as well as other AWS targets. Organizations can then tailor their data integration strategy to specific business needs. Data consistency and latency challenges can be effectively managed through AWS and Precisely’s monitoring capabilities. By adopting this architecture, organizations keep their mainframe data continually available for analytics, machine learning (ML), and other advanced applications.Streaming mainframe data to AWS in near real time represents a strategic step toward modernizing legacy systems while unlocking new opportunities for innovation, with data transfers occurring in subseconds. With Precisely and AWS, organizations can effectively navigate their modernization journey and maintain their competitive advantage.

Learn more about AWS Mainframe Modernization – Data Replication for IBM z/OS AMI in the Precisely documentation. AWS Mainframe Modernization Data Replication is available for purchase in AWS Marketplace. For more information about the solution or to see a demonstration, contact Precisely.


About the authors

Supreet Padhi

Supreet Padhi

Supreet is a Technology Architect at Precisely. He has been with Precisely for more than 14 years, with specialty in streaming data use cases and technology, with emphasis on data warehouse architecture. He is responsible for research and development in areas such as Change Data Capture (CDC), streaming ETL, metadata management, and VectorDBs.

Manasa Ramesh

Manasa Ramesh

Manasa is a Technology Architect at Precisely, with over 15 years of experience in software development. She has worked on several innovation-driven projects in Metadata Management, Data Governance and Data Integration space. She is currently responsible for research, design and development of metadata discovery framework.

Tamara Astakhova

Tamara Astakhova

Tamara is a Sr. Partner Solutions Architect in Data and Analytics at AWS, brings over two decades of expertise in architecting and developing large-scale data analytics systems. In her current role, she collaborates with strategic partners to design and implement sophisticated AWS-optimized architectures. Her deep technical knowledge and experience make her an invaluable resource in helping organizations transform their data infrastructure and analytics capabilities.

Migrate encrypted Amazon EC2 instances across AWS Regions without sharing AWS KMS keys

Post Syndicated from Rakesh Mannepalli original https://aws.amazon.com/blogs/compute/migrate-encrypted-amazon-ec2-instances-across-aws-regions-without-sharing-aws-kms-keys/

At AWS, we’ve designed our global infrastructure with isolated AWS Regions to help you achieve high fault tolerance and stability for your applications. These AWS Regions are organized into partitions, each with distinct network and security boundaries.

As your business evolves, you might need to migrate workloads between AWS Regions. Perhaps you’re looking to reduce latency for users in new geographic areas, meet Region-specific compliance requirements, or you’re an ISV expanding your product’s availability. Whatever your motivation, cross-Region migration needs careful planning, especially when dealing with encrypted resources.

When migrating Amazon Elastic Compute Cloud (Amazon EC2) instances with encrypted Amazon Elastic Block Storage (Amazon EBS) volumes across AWS Regions with in the same account or a different account, you face a particular challenge: AWS Key Management Service (AWS KMS) keys are AWS Region-specific and cannot be shared across AWS Regions. This post provides a step-by-step approach to successfully migrate your encrypted EC2 instances without compromising your security posture by sharing your KMS keys.

Solution overview

The following diagram and steps are an overview of how an EC2 instance can be migrated to a different Region in a different account without sharing the KMS keys.

Figure 1:Design to migrate EC2 between two accounts

Figure 1:Design to migrate EC2 between two accounts

Prerequisites

The following prerequisites are necessary to complete this solution:

  • Create an S3 bucket in both the source and target Region.
  • Configure the target account Amazon S3 bucket with the following policy to copy the Amazon Machine Image (AMI) file between two accounts:
{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "Statement1",
            "Effect": "Allow",
            "Principal": {
                "AWS": "arn:aws:sts::1234567891:assumed-role/<rolename>"
            },
            "Action": [
                "s3:GetObject",
                "s3:PutObject",
                "s3:PutObjectAcl"
            ],
            "Resource": "arn:aws:s3:::<target-bucket-name>/*"
        }
    ]
}

Implementation steps

Now based on the above architecture, you are implementing the follow steps to move your EC2 instance from the source account to the target account

  1. Create an AMI of the server that you want to move to a different Region in the same account or different account.
    1. Choose the server
    2. Choose Actions, Image and templates, and Create image.

      Figure 2: steps to create an AMI

      Figure 2: steps to create an AMI

    3. Fill the details and choose Create Image.

      Figure 3: Confirming AMI creation attributes

      Figure 3: Confirming AMI creation attributes

  2. Check the status of the AMI by choosing AMI ID or under AMI on your left-hand side menu, wait until the status shows as Available.

    Figure 4: AMI availability status

    Figure 4: AMI availability status

  3. Run the following command using AWS CloudShell from the AWS console.
    aws ec2 create-store-image-task --image-id ami-xxxxxxxxx –bucket <bucket_name>

  4. You can check the status of the job using the following command to make sure it is completed.
    aws ec2 describe-store-image-tasks

    Figure 5: CloudShell command execution

    Figure 5: CloudShell command execution


  5. Now you can see your AMI bin file in the S3 bucket.

    Figure 6: .bin file in the source S3 bucket

    Figure 6: .bin file in the source S3 bucket

  6. Copy the AMI bin to the target S3 bucket using the following command from the CloudShell in the source account.
    aws s3 cp s3://<source_bucket>/ami-000xxxxxxxxx.bin s3://<target_bucket>/

  7. When the copy job is completed, validate the AMI’s availability in .bin format in the target AWS account S3 bucket.

    Figure 7: .bin file in the target S3 bucket

    Figure 7: .bin file in the target S3 bucket

  8. Now restore the .bin file as an AMI in the target account by running the following command in the target account CloudShell.
    aws ec2 create-restore-image-task --object-key ami-xxxx.bin --bucket <target_bucket> --name "<AMI_name>"

    Figure 8: CloudShell command execution

    Figure 8: CloudShell command execution


  9. Check the availability of the AMI under the EC2 section in the target. You should find a new AMI ID along with the source Region information.

    Figure 9: AMI created in the target account

    Figure 9: AMI created in the target account

  10. Launch the instance using the migrated AMI in the target Region.

    Figure 10: Launched EC2 instance in the target account

    Figure 10: Launched EC2 instance in the target account

Limitations

Following are the limitations with this process:

  • To store an AMI, your AWS account must either own the AMI and its snapshots, or the AMI and its snapshots must be shared directly with your account. You can’t store an AMI if it is only publicly shared.
  • Only Amazon EBS-backed AMIs can be stored using these APIs.
  • Paravirtual (PV) AMIs are not supported.
  • The size of an AMI (before compression) that can be stored is limited to 5,000 GB.
  • Quota on store image requests: 1,200 GB of storage work (snapshot data) in progress.
  • Quota on restore image requests: 600 GB of restore work (snapshot data) in progress.
  • For the duration of the store task, the snapshots must not be deleted and the AWS Identity and Access Management (IAM) principal doing the store must have access to the snapshots, otherwise the store process fails.
  • You can’t create multiple copies of an AMI in the same S3 bucket.
  • An AMI that is stored in an S3 bucket can’t be restored with its original AMI ID. You can mitigate this by using AMI aliasing.
  • Currently the store and restore APIs are only supported by using the AWS Command Line Interface (AWS CLI), AWS SDKs, and Amazon EC2 API. You can’t store and restore an AMI using the Amazon EC2 console.

Clean up resources

When you have successfully deployed the server in the target Region you can delete the S3 buckets that were created for this migration. You can also terminate EC2 and delete associated EBS volumes and snapshots if you do not need them to avoid additional cost.

Conclusion

In this post, we showed you how to migrate an Amazon EC2 instances into another Region in a different account without sharing any AWS KMS keys in a secured manner.

Securing applications with AWS Nitro Enclaves: TLS termination, TAP networking, and IMDSv2

Post Syndicated from David-Paul Dornseifer original https://aws.amazon.com/blogs/compute/securing-applications-with-aws-nitro-enclaves-tls-termination-tap-networking-and-imdsv2/

AWS Nitro Enclaves provide isolated environments that keep critical operations such as decryption and cryptographic key management secure from both from root user and external threats.

Many customers have applications that require end-to-end authentication using Transport Layer Security (TLS) and requiring control over TLS termination.

TLS termination refers to the process where encrypted TLS traffic is decrypted using the server’s private key, converting the secure encrypted communication back to plaintext for processing. TLS termination can be done directly within an enclave, helping to ensure that encrypted traffic is not exposed outside the trusted boundary.

This is particularly valuable for public-facing services such as anonymization proxies and Model Context Protocol (MCP) servers, where clients demand assurance that their communications are protected and the application’s integrity can be independently verified using cryptographic attestation in a remote fashion.

This post covers critical design and implementation decisions from the Build multi-party crypto wallets with AWS Nitro Enclaves workshop and the associated public GitHub repository.

Specifically, in this blog we explore patterns on how:

  1. you can build applications that are remotely verifiable by clients, including enclave-based TLS termination using Nitriding, an open-source framework built by Brave and AWS Nitro Enclaves.
  2. you can configure TAP networking devices for AWS Nitro Enclaves using gvproxy.
  3. your enclaves can access EC2 instance metadata service (IMDSv2) and fetch temporary AWS credentials.
  4. you can decrypt secrets via AWS Key Management Service (KMS) using cryptographic attestation and the Python Boto3 SDK.

Prerequisites and Deployment

This post builds on our workshop “Build multi-party crypto wallets with AWS Nitro Enclaves” which demonstrates a Shamir Secret Sharing (SSS) application. The SSS app securely splits cryptographic private keys into multiple shards, requiring a threshold number to reconstruct the original key, ideal for Nitro Enclaves as it prevents any single party from accessing the complete key while maintaining operational functionality.

To follow along hands-on, you’ll need to deploy the provided AWS Cloud Development Kit (CDK) stack from the workshop repository on GitHub. However, you can understand the concepts and architecture discussed in this post without deploying the solution yourself.

Solution architecture

The following diagram depicts the high-level architecture of the solution.

Comprehensive AWS architecture showing VPC networking, container deployment, security services, and managed database integration

Before we dive deep into the application design, lets introduce the high-level components enclosed in the AWS Cloud Development Kit (AWS CDK) stack:

  • A dedicated virtual private cloud (VPC) and private subnets are created. Internet access is only possible through a NAT gateway, avoiding public exposure of the Amazon Elastic Compute Cloud (EC2) instances.
  • EC2 instances are placed in several private subnets and in different Availability Zones (AZ) using the auto-scaling group (ASG) to provide high availability. Network Load Balancer (NLB) is used to distribute the requests between different EC2 instances in the ASG. Each EC2 instance has one AWS Nitro enclave associated.
  • AWS Key Management Service (AWS KMS) manages the symmetric key required for secure private key management using AWS Nitro Enclaves.
  • Amazon DynamoDB is used to store the key shards for the Shamir Secret Sharing (SSS) solution.

Application design

During the AWS CDK deployment process (shown in the following figure), the following application will be built and deployed to the EC2 instance and the associated enclave. You can review the Python source code for the different components in the public GitHub repository.

Detailed AWS Nitro Enclave security architecture illustrating attestation process, TLS certification, and DynamoDB integration

EC2 instance (left side)

  • gvproxy: Proxy component that manages outbound and inbound TCP to vsock connections.
  • watchdog: Systemd service that starts the enclave and makes sure it stays up and healthy.
  • imds proxy: Systemd service that forwards Instance Metadata calls originating from vsock to 169.254.169.254. This allows the enclave to request fresh IMDSv2 credentials.

Enclave (right side)

  • TAP interface: gvproxy counterpart. A fully routed network interface created by nitriding-daemon that allows inbound and outbound traffic routing in the enclave.
  • imds proxy: IMDS proxy counterpart that allows the enclave to request credentials from its parent instance metadata service.
  • nitriding-daemon: HTTPS service that terminates incoming HTTPS connections, responds to attestation requests, and forwards all /app* HTTP requests to the sss app HTTP listener.
  • SSS application: An SSS application that interacts with all AWS services such as AWS KMS or DynamoDB through Boto3 and provides key management and signing capabilities.
  • Nitro Secure Module: Enclave internal /dev/nsm device that provides attestation and random number generator capabilities. Attestation private/public keys are managed by AWS.

Enclave based TLS termination and Remote Validation

Let’s now see how we can achieve TLS termination inside the enclave and allow remote clients to verify the enclaves code.

To do so, we are using Nitriding, a Go toolkit that simplifies running web applications inside AWS Nitro Enclaves without requiring networking stack changes. It uses gvproxy to create a tap0 interface, enabling controlled inbound and outbound traffic for the application inside the enclave.

Let’s have a look at the most important features nitriding offers.

TLS Termination: Nitriding generates an ephemeral private/public key pair on first launch, issuing a self-signed certificate for TLS. Furthermore, it supports Let’s Encrypt certificates for production use.

Application integration: Nitriding terminates TLS and forwards all /app* HTTP requests to the HTTP listener of the configured application. In the workshop these requests are forwarded to the SSS application.

Attestation endpoint: By default, nitriding exposes an /attestation endpoint that accepts a nonce value and returns a signed cryptographic attestation document.

This cryptographic attestation document includes hash measurements, also referred to as platform configuration registers (PCR), such as the hash of the enclave images (PCR0) or details about the parent EC2 instance (PCR4). For details on these measurements, refer to Where to get an enclave’s measurements.

The attestation document supports optional, customizable fields, namely nonce, public-key and user_data, which can be set individually for every attestation doc. For more information on the Nitro Enclaves attestation process and document structure, refer to Nitro Enclaves Attestation Process or check out the workshop sections about Customizing Attestation or document Validation.

Nitriding adds the nonce to the attestation document as a measure of freshness. Furthermore, the fingerprint (hash) of TLS certificate used by the enclave, is being added to the user_data field, as shown in the following sequence diagram.

This binds the certificate to the specific enclave instance.

Detailed AWS Nitro Enclave attestation sequence showing vsock communication and system calls

By comparing the TLS certificate fingerprint presented during the HTTPs connection and the fingerprint in the attestation document, you can prove the following aspects:

  • The private key for TLS termination resides securely inside the enclave (in a trusted AWS environment).
  • The enclave is running trusted code, as verified by the attestation’s PCR (Platform Configuration Register) measurements.
  • The identity of the enclave is validated, whether the code is open source (allowing deterministic measurement through reproducible builds) or closed source (with measurements distributed by the provider). For more information on deterministic and reproducible builds, refer to Establishing verifiable security: Reproducible builds and AWS Nitro Enclaves.

Horizontal scaling

Let’s now have look into the scaling properties of a AWS Nitro Enclave based nitriding application and learn how we can improve the processing capacities of our application by scaling out horizontally.The provided CDK, by default, provisions a single EC2 instance with its associated enclave. As depicted in the preceding sequence diagram, nitriding generates a self-signed certificate at the start and uses it to terminate TLS connections. This approach is limited to a single worker because load balancing requests over several workers would introduce non-identical TLS certificates. Non-identical TLS certificates behind NLB can cause certificate mismatch errors and TLS handshake failures when clients are routed to different backend servers with certificates that don’t match (the expected domain name) or have different validation properties.There are different ways you can address this issue besides implementing your own cryptographic attestation-based method:

  • Create a symmetric KMS key and associate it with your enclaves using AWS KMS condition keys for AWS Nitro Enclaves. Use AWS Certificate Manager (ACM) to create an exportable TLS certificate. Alternatively, generate a custom TLS certificate in a trusted environment. Encrypt all sensitive key material via AWS KMS and store the ciphertext in a database such as DynamoDB. Provide the encrypted TLS certificate to each enclave that requires access and use cryptographic attestation to decrypt the TLS certificate or key.
  • Nitriding provides an enclave key synchronization mechanism based on AWS Nitro Enclaves cryptographic attestation. This mechanism supports Let’s Encrypt certificates out of the box so organizations can avoid all the operational and security challenges associated with self-signed certificates, particularly in context of web browsers.

Virtual Networking for Enclaves with Tap Interface

Now let’s deep dive into how nitriding provides tap0based networking (to the enclave) and learn how we can use tap0 networking without nitriding.

As mentioned previously, nitriding uses gvisor-tap-vsock package to provide tap0 based networking to the enclave.

gvisor-tap-vsock delivers a user-mode network stack for virtual machines (VMs) and containers, enabling secure, flexible connectivity between AWS Nitro Enclaves and external networks.

You can use gvisor-tap-vsock independently from nitriding if you only require tap0 networking without TLS termination and http forwarding capabilities. The setup remains the same as in the workshop; however instead of nitriding binary, you need to include the gvforwarder binary in the enclave Dockerfile. The build instructions can be found in Makefile.

After copying the binary into your Docker file, use a similar command in your enclave start.sh file to activate DNS resolution and start gvforwarder:

echo "nameserver 192.168.127.1" > /run/resolvconf/resolv.conf
./app/gvforwarder -url vsock://3:1024/connect &

After you have started your enclave with gvforwarder you can manage port forwarding using the gvproxy process running on EC2 parent instances as done in the workshop.

IMDSv2 access from inside Enclaves

This section explores the requirement of accessing EC2 Instance Metadata Service Version 2 (IMDSv2) from inside an enclave and discusses different ways on how access can be provided.

Applications inside AWS Nitro Enclaves often need access to IMDSv2 to obtain temporary AWS credentials to interact with AWS services such as AWS KMS for decrypt operations. IMDSv2 is only accessible from within the associated EC2 instance and can be accessed at 169.254.169.254.You can enable IMDSv2 access for enclaves using one of the following two approaches:

Dedicated vsock proxy route (as done in the workshop)

Run a vsock proxy on the EC2 parent instance and one inside the enclave to provide access to IMDSv2 from inside the enclave. Apply the following configuration to your enclave to map 169.254.169.254 from inside the enclave to the endpoint on the parent instance:

ip addr add 169.254.169.254/16 dev lo
IN_ADDRS=169.254.169.254:80 OUT_ADDRS=3:8002 ./app/proxy &

This method is suitable if you do not need a tap interface in the enclave and want to tightly control outbound communication.

TAP interface with gvisor-tap-vsock

If your enclave uses a tap interface via gvisor, pass the -ec2-instance-metadata flag in the gvisor start command on the parent EC2 instance. This allows the host process to forward IMDSv2 traffic from the enclave (via tap0) to the metadata service. Ensure you are using gvisor-tap-vsock version v0.8.7 or newer for this feature.

Any of the EC2 parent instance or enclave related changes described in this section can be applied to an existing workshop CDK stack by rerunning the cdk deploy command as described here: Deploy the CDK application.

Encrypting and decrypting secrets inside AWS Nitro Enclaves using Python and Cryptographic Attestation

In this section we will go in depth on how KMS based decryption can be implemented inside enclaves in Python using AWS SDK for Python (Boto3).

Decryption, leverages the enclave’s unique cryptographic attestation feature unavailable directly on standard EC2 instances – ensuring enhanced security by verifying the enclave’s integrity.Encryption inside an enclave using the Boto3 SDK however mirrors the process outside the enclave, so it’s not detailed here.

High-Level Decryption Flow

The process for decrypting content inside a Nitro Enclave follows these streamlined steps:

  1. Ensure that the enclave has outbound networking configured.
  2. Generate an ephemeral RSA key pair.
  3. Request an attestation document that includes the public key.
  4. Create a KMS decrypt request with the ciphertext and attached attestation document.
  5. Receive and parse the resulting ciphertext_for_recipient in Cryptographic Message Syntax (CMS) format.

This flow enables secure decryption in Python, aligning with workshop examples for practical implementation.

Make sure that the tap0 network Interface is up and running and DNS has been configured

The Python code example discussed uses Boto3 SDK. Boto3 requires a fully routed network interface such as tap0 as described previously and access to AWS credentials. The credentials can be managed manually as done in the workshop or managed automatically by the SDK. See the previous section about managing AWS credentials.

Generate an ephemeral RSA key pair inside the enclave

Generate a fresh RSA private/public key pair for each session. This key is just used for the re-encryption schema and does not need persisted.

from cryptography.hazmat.primitives.asymmetric import rsa
private_key = rsa.generate_private_key(
    public_exponent=65537,
    key_size=2048,
)
public_key = private_key.public_key() 

Request an attestation document included the public key

Use the Nitro Secure Module (NSM) to generate an attestation document that cryptographically proves enclave identity and includes the ephemeral public key.

import base64
import aws_nsm_interface_verifiably
file_desc = aws_nsm_interface_verifiably.open_nsm_device()
attestation_doc = aws_nsm_interface_verifiably.get_attestation_doc(
    file_desc, public_key=public_key_raw)["document"]
attestation_doc_b64 = base64.b64encode(attestation_doc).decode("utf-8") 

AWS Nitro Enclaves SDK for C can be used along with Python to interact with the NSM device as done in the Validate a Nitro Enclave Attestation Document sample code repository.

Create an AWS KMS decrypt request including the ciphertext and attestation document

Send the attestation document as part of the Recipient parameter in the AWS KMS decrypt API call. AWS KMS will verify the attestation and encrypt the response for your enclave’s public key.

response = kms_client.decrypt(
    KeyId=ssm_params["KMSKeyID"],
    CiphertextBlob=base64.standard_b64decode(ciphertext_blob_b64),
    Recipient={
        "KeyEncryptionAlgorithm": "RSAES_OAEP_SHA_256",
        "AttestationDocument": base64.standard_b64decode(attestation_doc_b64),
    },
)

Receive and parse the ciphertext_for_recipient CMS document

AWS KMS returns a Cryptographic Message Syntax (CMS) structure containing the encrypted symmetric key and ciphertext. To decrypt, use the following steps:

  1. Load the private key from Step 2
from cryptography.hazmat.primitives import serialization
with open(private_key_file, "rb") as f:
    private_key_raw = f.read()
private_key = serialization.load_der_private_key(private_key_raw, 
                                   password=None)
  1. Parse the CMS structure

Use a library such as asn1crypto to extract the encrypted key, initialization vector (IV), and encrypted content.

from asn1crypto import cms
content_info = cms.ContentInfo.load(ciphertext_for_recipient)
enveloped_data = content_info["content"]
recipient_infos = enveloped_data["recipient_infos"][0].chosenencrypted_key = recipient_infos["encrypted_key"].native
encrypted_content_info = enveloped_data["encrypted_content_info"]
content_encryption_algorithm = encrypted_content_info["content_encryption_algorithm"]
iv = content_encryption_algorithm["parameters"].native
encrypted_content = encrypted_content_info["encrypted_content"].native
  1. Decrypt the symmetric key

CMS uses private/public key cryptography to encrypt a symmetric key that is used for the payload. Use the enclave’s RSA private key to decrypt the symmetric key with OAEP padding.

from cryptography.hazmat.primitives.asymmetric import padding
from cryptography.hazmat.primitives import hashes
decrypted_sym_key = private_key.decrypt(
    encrypted_key,
    padding.OAEP(
        mgf=padding.MGF1(algorithm=hashes.SHA256()),
        algorithm=hashes.SHA256(),
        label=None,
    ),
)
  1. Decrypt the content with Advanced Encryption Standard (AES)

Use the decrypted symmetric key and IV to decrypt the content (typically using AES-CBC).

from cryptography.hazmat.primitives.ciphers import Cipher, algorithms, modes
from cryptography.hazmat.backends import default_backend
from cryptography.hazmat.primitives import padding as sym_padding
cipher = Cipher(
    algorithms.AES(decrypted_sym_key), modes.CBC(iv), backend=default_backend()
)
decryptor = cipher.decryptor()
decrypted_padded = decryptor.update(encrypted_content) + decryptor.finalize()
unpadder = sym_padding.PKCS7(128).unpadder()
decrypted_content = unpadder.update(decrypted_padded) + unpadder.finalize()
  1. Encode the content for transport

Encode the decrypted content as base64 for safe transport or further processing.

import base64
result = base64.b64encode(decrypted_content).decode("utf-8")

Cleanup

To avoid incurring future charges, delete the resources following the steps described in the workshop Cleanup section.

Conclusion

In this post, you learned how to use AWS Nitro Enclaves for building secure (public) applications using TLS termination, cryptographic attestation and TAP networking. The implementation includes practical examples using gvisor-tap-vsock tap networking, secure IMDSv2 access patterns and Python based CMS decrypt..

Ready to enhance your application security? Visit our GitHub repository and workshop to start building with AWS Nitro Enclaves today.

Integrate Amazon CloudWatch alarms with WhatsApp using AWS End User Messaging

Post Syndicated from Ruchikka Chaudhary original https://aws.amazon.com/blogs/messaging-and-targeting/integrate-amazon-cloudwatch-alarms-with-whatsapp-using-aws-end-user-messaging/

Timely and accessible alert notifications are crucial for maintaining operational excellence, but traditional alerting mechanisms often fall short. Email notifications can get buried in crowded inboxes, SMS messages might incur high costs for international teams, and pager systems lack the rich context modern teams need for rapid incident response. WhatsApp, with over 2 billion users worldwide, offers several advantages:

  • Universal accessibility – Available on virtually every smartphone
  • Rich media support – Sends formatted messages, images, and links
  • Global reach – No international SMS fees
  • High engagement – Messages are typically delivered within seconds
  • Familiar interface – Many teams already use WhatsApp for daily communication

This post walks through a solution to build a serverless alerting system that delivers Amazon CloudWatch alarms to WhatsApp using AWS End User Messaging.

Overview of solution

The solution uses AWS End User Messaging Social to create a seamless bridge between CloudWatch alarms and WhatsApp notifications. This serverless architecture provides real-time infrastructure alerts through WhatsApp messaging platform teams already know and use.

The architecture consists of four main AWS services working together. The data flow begins when CloudWatch alarms detect breaches of predefined thresholds and publish notifications to an Amazon Simple Notification Service (Amazon SNS) topic. The SNS topic triggers an AWS Lambda function that processes the alarm data, formats contextual WhatsApp messages, and uses AWS End User Messaging Social to deliver notifications to specified recipients.

The following diagram illustrates the solution architecture.

Prerequisites

Implementation requires an AWS account with appropriate permissions for AWS CloudFormation, Lambda, Amazon SNS, and CloudWatch. You must also have a WhatsApp Business Account integrated with AWS End User Messaging and the WhatsApp phone number ID from the AWS End User Messaging console. (For instructions to locate this information, see View a phone number’s ID in AWS End User Messaging Social).

For more information about how to set up WhatsApp using AWS End User Messaging Social, refer to Automate workflows with WhatsApp using AWS End User Messaging Social.

Before you deploy this solution, create an approved template in your Meta account named cw_alarm_notification. Alternatively, use your preferred template name and modify the Lambda function code accordingly (as shown in the following screenshot).

Lambda function code

The solution uses a Python-based Lambda function that processes CloudWatch alarm notifications and formats them for WhatsApp delivery. The function receives SNS events containing CloudWatch alarm data, extracts relevant information, formats contextual messages, and delivers notifications through AWS End User Messaging Social.

The following function code shows an example to parse the SNS message content and extract key alarm information, including alarm name, state value, and reason for state change:

def process_alarm_notification(record):
    # Parse SNS message
    sns_message = json.loads(record['Sns']['Message'])
    
    # Extract alarm details
    alarm_name = sns_message.get('AlarmName', 'Unknown Alarm')
    alarm_description = sns_message.get('AlarmDescription', '')
    new_state = sns_message.get('NewStateValue', 'UNKNOWN')
    old_state = sns_message.get('OldStateValue', 'UNKNOWN')
    reason = sns_message.get('NewStateReason', '')
    timestamp = sns_message.get('StateChangeTime', '')
    region = sns_message.get('Region', '')
    
    # Format WhatsApp message
    message = format_alarm_message(
        alarm_name, alarm_description, new_state, 
        old_state, reason, timestamp, region
    )
    
    # Send WhatsApp message
    send_whatsapp_message(message)
    

The following code shows an example to create a template message for WhatsApp (you can change the template name if required):

              # Build message
              template_name = 'cw_alarm_notification'
              template_message = {
                      "name": template_name,
                      "language": {
                          "code": "en"
                      },
                      "components": [
                          {
                              "type": "header",
                              "parameters": [{
                                  "type": "text",
                                  "parameter_name": "emoji",
                                  "text": state_emoji
                                  }
                              ]
                          },
                          {
                              "type": "body",
                              "parameters": [
                                  {
                                      "type": "text",
                                      "parameter_name": "alarm_name",
                                      "text": alarm_name
                                  },
                                  {
                                      "type": "text",
                                      "parameter_name": "status",
                                      "text": old_state + " → " + new_state
                                  },
                                  {
                                      "type": "text",
                                      "parameter_name": "region_account",
                                      "text": region + " - " + account_id
                                  },
                                  {
                                      "type": "text",
                                      "parameter_name": "time",
                                      "text": formatted_time
                                  },
                                  {
                                      "type": "text",
                                      "parameter_name": "description",
                                      "text": alarm_description + reason
                                  }
                              ]
                          }

                      ]
                  }
              
              return template_message

The send_whatsapp_message function uses AWS End User Messaging Social to deliver formatted messages through the socialmessaging client:

def send_whatsapp_message(message):
    """Send message via AWS End User Messaging"""
    client = boto3.client('socialmessaging')
    
    response = client.send_whats_app_message(
        originationPhoneNumberId=os.environ['WHATSAPP_PHONE_NUMBER_ID'],
        destinationPhoneNumber=os.environ['ALERT_RECIPIENT'],
        messageBody={'text': message}
    )

Deploy the solution

The solution uses AWS CloudFormation for infrastructure as code (IaC) deployment. The main template creates an SNS topic for alarm notifications, a Lambda function for message processing, and required AWS Identity and Access Management (IAM) roles with least-privilege permissions.

The CloudFormation template requires a recipient number with an active WhatsApp account to receive alarm notifications as messages. The template also requires the WhatsApp phone number ID retrieved from the AWS End User Messaging Social console, as noted in the prerequisites. The template must be deployed in the same AWS Region as AWS End User Messaging Social. See the following code:

aws cloudformation deploy \
  --template-file <cloudwatch-eum-whatsapp-alerts.yaml> \
  --stack-name cloudwatch-eum-whatsapp-alerts \
  --parameter-overrides \
    WhatsAppPhoneNumberId=<your-phone-number-id-from-eum> \
    AlertRecipient=<+1234567890> \
    Environment=dev \
  --capabilities CAPABILITY_IAM \
  --region <EUM-region>

The preceding template deploys an alarm called SampleHighCPUAlarm that triggers an SNS topic. The SNS topic triggers the WhatsApp alarm notifier Lambda function, which processes and sends the message using AWS End User Messaging Social.

Test the solution

You can test the solution using the sample alarm created by the CloudFormation stack. The following screenshot shows an example alarm configuration and its CloudWatch metrics, currently in the OK state.

You can use the following code to trigger the alarm by updating this metric:

 aws cloudwatch put-metric-data --namespace "Custom/EC2" --metric-data MetricName=CPUUtilization,Value=85,Unit=Percent

As the alarm switches from OK to ALARM state, a WhatsApp Message is delivered.

Conclusion

Integrating CloudWatch with WhatsApp notifications represents a significant step forward in modern infrastructure monitoring. By using AWS End User Messaging, teams can receive critical alerts through their preferred communication channel while maintaining the reliability and scalability of AWS services.

The solution’s modular architecture, simple yet effective security model, and cost-effective design make it suitable for organizations of various sizes.


About the author

Visualize data lineage using Amazon SageMaker Catalog for Amazon EMR, AWS Glue, and Amazon Redshift

Post Syndicated from Shubham Purwar original https://aws.amazon.com/blogs/big-data/visualize-data-lineage-using-amazon-sagemaker-catalog-for-amazon-emr-aws-glue-and-amazon-redshift/

Amazon SageMaker offers a comprehensive hub that integrates data, analytics, and AI capabilities, providing a unified experience for users to access and work with their data. Through Amazon SageMaker Unified Studio, a single and unified environment, you can use a wide range of tools and features to support your data and AI development needs, including data processing, SQL analytics, model development, training, inference, and generative AI development. This offering is further enhanced by the integration of Amazon Q and Amazon SageMaker Catalog, which provide an embedded generative AI and governance experience, helping users work efficiently and effectively across the entire data and AI lifecycle, from data preparation to model deployment and monitoring.

With the SageMaker Catalog data lineage feature, you can visually track and understand the flow of your data across different systems and teams, gaining a complete picture of your data assets and how they’re connected. As an OpenLineage-compatible feature, it helps you trace data origins, track transformations, and view cross-organizational data consumption, giving you insights into cataloged assets, subscribers, and external activities. By capturing lineage events from OpenLineage-enabled systems or through APIs, you can gain a deeper understanding of your data’s journey, including activities within SageMaker Catalog and beyond, ultimately driving better data governance, quality, and collaboration across your organization.

Additionally, the SageMaker Catalog data lineage feature versions each event, so you can track changes, visualize historical lineage, and compare transformations over time. This provides valuable insights into data evolution, facilitating troubleshooting, auditing, and data integrity by showing exactly how data assets have evolved, and generates trust in data.

In this post, we discuss the visualization of data lineage in SageMaker Catalog and how capture lineage from different AWS analytics services such as AWS Glue, Amazon Redshift, and Amazon EMR Serverless automatically, and visualize it with SageMaker Unified Studio.

Solution overview

The generation of data lineage in SageMaker Catalog operates through an automated system that captures metadata and relationships between different data artifacts for AWS Glue, Amazon EMR, and Amazon Redshift. When data moves through various AWS services, SageMaker automatically tracks these movements, transformations, and dependencies, creating a detailed map of the data’s journey. This tracking includes information about data sources, transformations, processing steps, and final outputs, providing a complete audit trail of data movement and transformation.

The implementation of data lineage in SageMaker Catalog offers several key benefits:

  • Compliance and audit support – Organizations can demonstrate compliance with regulatory requirements by showing complete data provenance and transformation history
  • Impact analysis – Teams can assess the potential impact of changes to data sources or transformations by understanding dependencies and relationships in the data pipeline
  • Troubleshooting and debugging – When issues arise, the lineage system helps identify the root cause by showing the complete path of data transformation and processing
  • Data quality management – By tracking transformations and dependencies, organizations can better maintain data quality and understand how data quality issues might propagate through their systems

Lineage capture is automated using several tools in SageMaker Unified Studio. To learn more, refer to Data lineage support matrix.

In the following sections, we show you how to configure your resources and implement the solution. For this post, we create the solution resources in the us-west-2 AWS Region using an AWS CloudFormation template.

Prerequisites

Before getting started, make sure you have the following:

Configure SageMaker Unified Studio with AWS CloudFormation

The vpc-analytics-lineage-sus.yaml stack creates a VPC, subnet, security group, IAM roles, NAT gateway, internet gateway, Amazon Elastic Compute Cloud (Amazon EC2) client, S3 buckets, SageMaker Unified Studio domain, and SageMaker Unified Studio project. To create the solution resources, complete the following steps:

  1. Launch the stack vpc-analytics-lineage-sus using the CloudFormation template:
  2. Provide the parameter values as listed in the following table.

    Parameters Sample value
    DatazoneS3Bucket s3://datazone-{account_id}/
    DomainName dz-studio
    EnvironmentName sm-unifiedstudio
    PrivateSubnet1CIDR 10.192.20.0/24
    PrivateSubnet2CIDR 10.192.21.0/24
    PrivateSubnet3CIDR 10.192.22.0/24
    ProjectName sidproject
    PublicSubnet1CIDR 10.192.10.0/24
    PublicSubnet2CIDR 10.192.11.0/24
    PublicSubnet3CIDR 10.192.12.0/24
    UsersList analyst
    VpcCIDR 10.192.0.0/16

The stack creation process can take approximately 20 minutes to complete. You can check the Outputs tab for the stack after the stack is created.

Next, we prepare source data, setup the AWS Glue ETL Job, Amazon EMR Serverless Spark Job and Amazon Redshift Job to generate the lineage and capture lineage from Amazon SageMaker Unified Studio

Prepare data

The following is example data from our CSV files:

attendance.csv

EmployeeID,Date,ShiftStart,ShiftEnd,Absent,OvertimeHours
E1000,2024-01-01,2024-01-01 08:00:00,2024-01-01 16:22:00,False,3
E1001,2024-01-08,2024-01-08 08:00:00,2024-01-08 16:38:00,False,2
E1002,2024-01-23,2024-01-23 08:00:00,2024-01-23 16:24:00,False,3
E1003,2024-01-09,2024-01-09 10:00:00,2024-01-09 18:31:00,False,0
E1004,2024-01-15,2024-01-15 09:00:00,2024-01-15 17:48:00,False,1

employees.csv

EmployeeID,Name,Department,Role,HireDate,Salary,PerformanceRating,Shift,Location
E1000,Employee_0,Quality Control,Operator,2021-08-08,33002.0,1,Night,Plant C
E1001,Employee_1,Maintenance,Supervisor,2015-12-31,69813.76,5,Evening,Plant B
E1002,Employee_2,Production,Technician,2015-06-18,46753.32,1,Evening,Plant A
E1003,Employee_3,Admin,Supervisor,2020-10-13,52853.4,5,Night,Plant A
E1004,Employee_4,Quality Control,Manager,2023-09-21,55645.27,5,Evening,Plant A

Upload the sample data from attendance.csv and employees.csv to the S3 bucket specified in the previous CloudFormation stack (s3://datazone-{account_id}/csv/).

Ingest employee data in Amazon Relational Database Dervice (Amazon RDS) for MySQL table

On the CloudFormation console, open the stack vpc-analytics-lineage-sus and collect the Amazon RDS for MySQL database endpoint to use in the following commands to create a default employeedb database.

  1. Connect to Amazon EC2 instance with mysql package installation
  2. Run the following command to connect to the database
    >MySQL -u admin -h database-1.cuqd06l5efvw.us-west-2.rds.amazonaws.com -p

  3. Run the following command to create an employee table
    Use employeedb;
    
    CREATE TABLE employee (
      EmployeeID longtext,
      Name longtext,
      Department longtext,
      Role longtext,
      HireDate longtext,
      Salary longtext,
      PerformanceRating longtext,
      Shift longtext,
      Location longtext
    );

  4. Running the following command to insert rows.
    INSERT INTO employee (EmployeeID, Name, Department, Role, HireDate, Salary, PerformanceRating, Shift, Location) VALUES ('E1000', 'Employee_0', 'Quality Control', 'Operator', '2021-08-08', 33002.00, 1, 'Night', 'Plant C'), ('E1001', 'Employee_1', 'Maintenance', 'Supervisor', '2015-12-31', 69813.76, 5, 'Evening', 'Plant B'), ('E1002', 'Employee_2', 'Production', 'Technician', '2015-06-18', 46753.32, 1, 'Evening', 'Plant A'), ('E1003', 'Employee_3', 'Admin', 'Supervisor', '2020-10-13', 52853.40, 5, 'Night', 'Plant A'), ('E1004', 'Employee_4', 'Quality Control', 'Manager', '2023-09-21', 55645.27, 5, 'Evening', 'Plant A');

Capture lineage from AWS Glue ETL job and notebook

To demonstrate the lineage, we set up an AWS Glue extract, transform, and load (ETL) job to read the employee data from an Amazon RDS for MySQL table and the employee attendance data from Amazon S3, and join both datasets. Finally, we write the data to Amazon S3 and create the attendance_with_emp1 table in the AWS Glue Data Catalog.

Create and configure AWS Glue job for lineage generation

Complete the following steps to create your AWS Glue ETL job:

  1. On the AWS Glue console, create a new ETL job with AWS Glue version 5.0.
  2. Enable Generate lineage events and provide the domain ID (retrieve from the CloudFormation template output for DataZoneDomainid; it will have the format dzd_xxxxxxxx)
  3. Use the following code snippet in the AWS Glue ETL job script. Provide the S3 bucket (bucketname-{account_id}) used in the preceding CloudFormation stack.
    from pyspark.sql import SparkSession
    from pyspark.sql import SparkSession, DataFrame
    from pyspark.sql.functions import *
    from pyspark.sql.types import *
    from pyspark import SparkContext
    from pyspark.sql import SparkSession
    import sys
    import logging
    
    
    spark = SparkSession.builder.appName("lineageglue").enableHiveSupport().getOrCreate()
     
    connection_details = glueContext.extract_jdbc_conf(connection_name="connectionname")
    
    employee_df = spark.read.format("jdbc").option("url", "jdbc:MySQL://dbhost:3306/database_name").option("dbtable", "employee").option("user", connection_details['user']).option("password", connection_details['password']).load()
    
    s3_paths = {
    'absent_data': 's3://bucketname-{account_id}/csv/attendance.csv'
    }
    absent_df = spark.read.csv(s3_paths['absent_data'], header=True, inferSchema=True)
    
    joined_df = employee_df.join(absent_df, on="EmployeeID", how="inner")
    
    joined_df.write.mode("overwrite").format("parquet").option("path", "s3://datazone-{account_id}/attendanceparquet/").saveAsTable("gluedbname.tablename")

  4. Choose Run to start the job.
  5. On the Runs tab, confirm the job ran without failure.
  6. After the job has executed successfully, navigate to the SageMaker Unified Studio domain.
  7. Choose Project and under Overview, choose Data Sources.
  8. Select the Data Catalog source (accountid-AwsDataCatalog-glue_db_suffix-default-datasource).
  9. On the Actions dropdown menu, choose Edit.
  10. Under Connection, enable Import data lineage.
  11. In the Data Selection section, under Table Selection Criteria, provide a table name or use * to generate lineage.
  12. Update the data source and choose Run to create an asset called attendance_with_emp1 in SageMaker Catalog.
  13. Navigate to Assets, choose the attendance_with_emp1 asset, and navigate to the LINEAGE section.

The following lineage diagram shows an AWS Glue job that integrates data from two sources: employee information stored in Amazon RDS for MySQL and employee absence records stored in Amazon S3. The AWS Glue job combines these datasets through a join operation, then creates a table in the Data Catalog and registers it as an asset in SageMaker Catalog, making the unified data available for further analysis or machine learning purposes.

Create and configure AWS Glue notebook for lineage generation

Complete the following steps to create the AWS Glue notebook:

  1. On the AWS Glue console, choose Author using an interactive code notebook.
  2. Under Options, choose Start fresh and choose Create notebook.
  3. In the notebook, use the following code to generate lineage.

    In the following code, we add the required Spark configuration to generate lineage and then read CSV data from Amazon S3 and write in Parquet format to the Data Catalog table. The Spark configuration includes the following parameters:

    • spark.extraListeners=io.openlineage.spark.agent.OpenLineageSparkListener – Registers the OpenLineage listener to capture Spark job execution events and metadata for lineage tracking
    • spark.openlineage.transport.type=amazon_datazone_api – Specifies Amazon DataZone as the destination service where the lineage data will be sent and stored
    • spark.openlineage.transport.domainId=dzd_xxxxxxx – Defines the unique identifier of your Amazon DataZone domain where the lineage data will be associated
    • spark.glue.accountId={account_id} – Specifies the AWS account ID where the AWS Glue job is running for proper resource identification and access
    • spark.openlineage.facets.custom_environment_variables – Lists the specific environment variables to capture in the lineage data for context about the AWS and AWS Glue environment
    • spark.glue.JOB_NAME=lineagenotebook – Sets a unique identifier name for the AWS Glue job that will appear in lineage tracking and logs

    See the following code:

    %%configure —name project.spark -f
    {
    "—conf":"spark.extraListeners=io.openlineage.spark.agent.OpenLineageSparkListener \
    --conf spark.openlineage.transport.type=amazon_datazone_api \
    --conf spark.openlineage.transport.domainId=dzd_xxxxxxxx \
    --conf spark.glue.accountId={account_id} \
    --conf spark.openlineage.facets.custom_environment_variables=[AWS_DEFAULT_REGION;GLUE_VERSION;GLUE_COMMAND_CRITERIA;GLUE_PYTHON_VERSION;] \
    --conf spark.glue.JOB_NAME=lineagenotebook"
    }
    
    from pyspark.sql import SparkSession
    from pyspark.sql import SparkSession, DataFrame
    from pyspark.sql.functions import *
    from pyspark.sql.types import *
    from pyspark import SparkContext
    from pyspark.sql import SparkSession
    import sys
    import logging
    
    
    spark = SparkSession.builder.appName("lineagegluenotebook").enableHiveSupport().getOrCreate()
    
    s3_paths = {
    'absent_data': 's3://datazone-{account_id}/csv/attendance.csv'
    }
    absent_df = spark.read.csv(s3_paths['absent_data'], header=True, inferSchema=True)
    
    absent_df.write.mode("overwrite").format("parquet").option("path", "s3://datazone-{account_id}/attendanceparquet2/").saveAsTable("gluedbname.tablename")

  4. After the notebook has executed successfully, navigate to the SageMaker Unified Studio domain.
  5. Choose Project and under Overview, choose Data Sources.
  6. Choose the Data Catalog source ({account_id}-AwsDataCatalog-glue_db_suffix-default-datasource).
  7. Choose Run to create the asset attendance_with_empnote in SageMaker Catalog.
  8. Navigate to Assets, choose the attendance_with_empnote asset, and navigate to the LINEAGE section.

The following lineage diagram shows an AWS Glue job that reads data from the employee absence records stored in Amazon S3. The AWS Glue job transform CSV data into Parquet format, then creates a table in the Data Catalog and registers it as an asset in SageMaker Catalog.

Capture lineage from Amazon Redshift

To demonstrate the lineage, we are creating an employee table and an attendance table and join both datasets. Finally, we create a new table called employeewithabsent in Amazon Redshift. Complete the following steps to create and configure lineage for Amazon Redshift tables:

  1. In SageMaker Unified Studio, open your domain.
  2. Under Compute, choose Data warehouse.
  3. Open project.redshift and copy the endpoint name (redshift-serverless-workgroup-xxxxxxx).
  4. On the Amazon Redshift console, open the Query Editor v2, and connect to the Redshift Serverless workgroup with a secret. Use the AWS Secrets Manager option and choose the secret redshift-serverless-namespace-xxxxxxxx.
  5. Use the following code to create tables in Amazon Redshift and load data from Amazon S3 using the COPY command. Make sure the IAM role has GetObject permission on the S3 files attendance.csv and employees.csv.

    Create Redshift table absent

    CREATE TABLE public.absent (
        employeeid character varying(65535),
        date date,
        shiftstart timestamp without time zone ,
        shiftend timestamp without time zone,
        absent boolean,
        overtimehours integer
    );

    Load data into absent table.

    COPY absent
    FROM 's3://datazone-{account_id}/csv/attendance.csv' 
    IAM_ROLE 'arn:aws:iam::accountid:role/RedshiftAdmin'
    csv
    IGNOREHEADER 1;

    Create Redshift table employee

    CREATE TABLE public.employee (
        employeeid character varying(65535),
        name character varying(65535),
        department character varying(65535),
        role character varying(65535),
        hiredate date,
        salary double precision,
        performancerating integer,
        shift character varying(65535),
        location character varying(65535)
    );

    Load data into employee table.

    COPY employee
    FROM 's3://datazone-{account_id}/csv/employees.csv' 
    IAM_ROLE 'arn:aws:iam::account-id:role/RedshiftAdmin'
    csv
    IGNOREHEADER 1;

  6. After the tables are created and the data is loaded, perform the join between the tables and create a new table with a CTAS query:
    CREATE TABLE public.employeewithabsent AS
    SELECT 
      e.*,
      a.absent,
      a.overtimehours
    FROM public.employee e
    INNER JOIN public.absent a
    ON e.EmployeeID = a.EmployeeID;

  7. Navigate to the SageMaker Unified Studio domain.
  8. Choose Project and under Overview, choose Data Sources.
  9. Select the Amazon Redshift source (RedshiftServerless-default-redshift-datasource).
  10. On the Actions dropdown menu, choose Edit.
  11. Under Connection, Enable Import data lineage.
  12. In the Data Selection section, under Table Selection Criteria, provide a table name or use * to generate lineage.
  13. Update the data source and choose Run to create an asset called employeewithabsent in SageMaker Catalog.
  14. Navigate to Assets, choose the employeewithabsent asset, and navigate to the LINEAGE section.

The following lineage diagram shows joining two redshift tables and creating a new redshift table and registers it as an asset in SageMaker Catalog.

Capture lineage from EMR Serverless job

To demonstrate the lineage, we read employee data from an RDS for MySQL table and an attendance dataset from Amazon Redshift, and join both datasets. Finally, we write the data to Amazon S3 and create the attendance_with_employee table in the Data Catalog. Complete the following steps:

  1. On the Amazon EMR console, choose EMR Serverless in the navigation pane.
  2. To create or manage EMR Serverless applications, you need the EMR Studio UI.
    1. If you already have an EMR Studio in the Region where you want to create an application, choose Manage applications to navigate to your EMR Studio, or select the EMR Studio that you want to use.
    2. If you don’t have an EMR Studio in the Region where you want to create an application, choose Get started and then choose Create and launch Studio. EMR Serverless creates an EMR Studio for you so you can create and manage applications.
  3. In the Create studio UI that opens in a new tab, enter the name, type, and release version for your application.
  4. Choose Create application.
  5. Create an EMR Spark serverless application with the following configuration:
    1. For Type, choose Spark.
    2. For Release version, choose emr-7.8.0.
    3. For Architecture, choose x86_64.
    4. For Application setup options, select Use custom settings.
    5. For Interactive endpoint, enable the endpoint for EMR Studio.
    6. For Application configuration, use the following configuration:
      [{
          "Classification": "iceberg-defaults",
          "Properties": {
              "iceberg.enabled": "true"
          }
      }]

  6. Choose Create and Start application.
  7. After application has started, submit the Spark application to generate lineage events. Copy the following script and upload it to the S3 bucket (s3://datazone-{account_id}/script/). Upload the MySQL-connector-java JAR file to the S3 bucket (s3://datazone-{account_id}/jars/) to read the data from MySQL.
    from pyspark.sql import SparkSession
    from pyspark.sql import SparkSession, DataFrame
    from pyspark.sql.functions import *
    from pyspark.sql.types import *
    from pyspark import SparkContext
    from pyspark.sql import SparkSession
    import sys
    import logging
    
    
    spark = SparkSession.builder.appName("lineageglue").enableHiveSupport().getOrCreate()
    
    employee_df = spark.read.format("jdbc").option("driver","com.MySQL.cj.jdbc.Driver").option("url", "jdbc:MySQL://dbhostname:3306/databasename").option("dbtable", "employee").option("user", "admin").option("password", "xxxxxxx").load()
    
    absent_df = spark.read.format("jdbc").option("url", "jdbc:redshift://redshiftserverlessendpoint:5439/dev").option("dbtable", "public.absent").option("user", "admin").option("password", "xxxxxxxxxx").load()
    
    joined_df = employee_df.join(absent_df, on="EmployeeID", how="inner")
    
    joined_df.write.mode("overwrite").format("parquet").option("path", "s3://datazone-{account_id}/emrparquetnew/").saveAsTable("gluedname.tablename")

  8. After you upload the script, use the following command to submit the Spark application. Change the following parameters according to your environment details:
    1. application-id: Provide the Spark application ID you generated.
    2. execution-role-arn: Provide the EMR execution role.
    3. entryPoint: Provide the Spark script S3 path.
    4. domainID: Provide the domain ID (from the CloudFormation template output for DataZoneDomainid: dzd_xxxxxxxx).
    5. accountID: Provide your AWS account ID.
      aws emr-serverless start-job-run --application-id 00frv81tsqe0ok0l --execution-role-arn arn:aws:iam::{account_id}:role/service-role/AmazonEMR-ExecutionRole-1717662744320 --name "Spark-Lineage" --job-driver '{
              "sparkSubmit": {
                  "entryPoint": "s3://datazone-{account_id}/script/emrspark2.py",
                  "sparkSubmitParameters": "--conf spark.executor.cores=1 --conf spark.executor.memory=4g --conf spark.driver.cores=1 --conf spark.driver.memory=4g --conf spark.executor.instances=2 --conf spark.hadoop.hive.metastore.client.factory.class=com.amazonaws.glue.catalog.metastore.AWSGlueDataCatalogHiveClientFactory --conf spark.jars=/usr/share/aws/datazone-openlineage-spark/lib/DataZoneOpenLineageSpark-1.0.jar,s3://datazone-{account_id}/jars/MySQL-connector-java-8.0.20.jar --conf spark.extraListeners=io.openlineage.spark.agent.OpenLineageSparkListener --conf spark.openlineage.transport.type=amazon_datazone_api --conf spark.openlineage.transport.domainId=dzd_xxxxxxxx --conf spark.glue.accountId={account_id}"
              }
          }'

  9. After the job has executed successfully, navigate to the SageMaker Unified Studio domain.
  10. Choose Project and under Overview, choose Data Sources.
  11. Select the Data Catalog source ({account_id}-AwsDataCatalog-glue_db_xxxxxxxxxx-default-datasource).
  12. On the Actions dropdown menu, choose Edit.
  13. Under Connection, enable Import data lineage.
  14. In the Data Selection section, under Table Selection Criteria, provide a table name or use * to generate lineage.
  15. Update the data source and choose Run to create an asset called attendancewithempnew in SageMaker Catalog.
  16. Navigate to Assets, choose the attendancewithempnew asset, and navigate to the LINEAGE section.

The following lineage diagram shows an AWS Glue job that integrates employee information stored in Amazon RDS for MySQL and employee absence records stored in Amazon Redshift. The AWS Glue job combines these datasets through a join operation, then creates a table in the Data Catalog and registers it as an asset in SageMaker Catalog.

Clean up

To clean up your resources, complete the following steps:

  1. On the AWS Glue console, delete the AWS Glue job.
  2. On the Amazon EMR console, delete the EMR Serverless Spark application and EMR Studio.
  3. On the AWS CloudFormation console, delete the CloudFormation stack vpc-analytics-lineage-sus.

Conclusion

In this post, we showed how data lineage in SageMaker Catalog helps you track and understand the complete lifecycle of your data across various AWS analytics services. This comprehensive tracking system provides visibility into how data flows through different processing stages, transformations, and analytical workflows, making it an essential tool for data governance, compliance, and operational efficiency.

Try out these lineage visualization methods for your own use cases, and share your questions and feedback in the comments section.


About the Authors

Shubham Purwar

Shubham Purwar

Shubham is an AWS Analytics Specialist Solution Architect. He helps organizations unlock the full potential of their data by designing and implementing scalable, secure, and high-performance analytics solutions on the AWS platform. With deep expertise in AWS analytics services, he collaborates with customers to uncover their distinct business requirements and create customized solutions that deliver actionable insights and drive business growth. In his free time, Shubham loves to spend time with his family and travel around the world.

Nitin Kumar

Nitin Kumar

Nitin is a Cloud Engineer (ETL) at Amazon Web Services, specialized in AWS Glue. With a decade of experience, he excels in aiding customers with their big data workloads, focusing on data processing and analytics. He is committed to helping customers overcome ETL challenges and develop scalable data processing and analytics pipelines on AWS. In his free time, he likes to watch movies and spend time with his family.

Prashanthi Chinthala

Prashanthi Chinthala

Prashanthi is a Cloud Engineer (DIST) at AWS. She helps customers overcome EMR challenges and develop scalable data processing and analytics pipelines on AWS.

Building a real-time ICU patient analytics pipeline with AWS Lambda event source mapping

Post Syndicated from Priyanka Chaudhary original https://aws.amazon.com/blogs/big-data/building-a-real-time-icu-patient-analytics-pipeline-with-aws-lambda-event-source-mapping/

In hospital intensive care units (ICUs), continuous patient monitoring is critical. Medical devices generate vast amounts of real-time data on vital signs such as heart rate, blood pressure, and oxygen saturation. The key challenge lies in early detection of patient deterioration through vital sign trending. Healthcare teams must process thousands of data points daily per patient to identify concerning patterns, a task crucial for timely intervention and potentially life-saving care.

AWS Lambda event source mapping can help in this scenario by automatically polling data streams and triggering functions in real-time without additional infrastructure management. By using AWS Lambda for real-time processing of sensor data and storing aggregated results in secure data structures designed for large analytic datasets called Iceberg tables in Amazon Simple Storage Service (Amazon S3) buckets, medical teams can achieve both immediate alerting capabilities and gain long-term analytical insights, enhancing their ability to provide timely and effective care.

In this post, we demonstrate how to build a serverless architecture that processes real-time ICU patient monitoring data using Lambda event source mapping for immediate alert generation and data aggregation, followed by persistent storage in Amazon S3 with an Iceberg catalog for comprehensive healthcare analytics. The solution demonstrates how to handle high-frequency vital sign data, implement critical threshold monitoring, and create a scalable analytics platform that can grow with your healthcare organization’s needs and help monitor sensor alert fatigue in the ICU.

Architecture

The following architecture diagram illustrates a real-time ICU patient analytics system.

Arch diagram

In this architecture, real-time patient monitoring data from hospital ICU sensors is ingested into AWS IoT Core, which then streams the data into Amazon Kinesis Data Streams. Two Lambda functions consume this streaming data concurrently for different purposes, both using Lambda event source mapping integration with Kinesis Data Streams. The first Lambda function uses the filtering feature of event source mapping to detect critical health events where SpO2(blood oxygen saturation) levels fall below 90%, immediately triggering notifications to caregivers through Amazon Simple Notification Service (Amazon SNS) for rapid response. The second Lambda function employs the tumbling window feature of event source mapping to aggregate sensor data over 10-minute time intervals. This aggregated data is then systematically stored in S3 buckets in Apache Iceberg format for historical analysis and reporting. The entire pipeline operates in a serverless manner, providing scalable, real-time processing of critical healthcare data while maintaining both immediate alerting capabilities and long-term data storage for analytics.

Amazon S3 data, with its support for Apache Iceberg table format, enables healthcare organizations to efficiently store and query large volumes of time-series patient data. This solution allows for complex analytical queries across historical patient data while maintaining high performance and cost efficiency.

Prerequisites

To implement the solution provided in this post, you should have the following:

  • An active AWS account
  • IAM permissions to deploy CloudFormation templates and provision AWS resources
  • Python installed on your machine to run the ICU patient sensor data simulator code

Deploy a real-time ICU patient analytics pipeline using CloudFormation

You use AWS CloudFormation templates to create the resources for a real-time data analytics pipeline.

  1. To get started, Sign in to the console as Account user and select the appropriate Region.
  2. Download and launch CloudFormation template  where you want to host the Lambda functions.
  3. Choose Next.
  4. On the Specify stack details page, enter a Stack name (for example, IoTHealthMonitoring).
  5. For Parameters, enter the following:
    1. IoTTopic: Enter the MQTT topic for your IoT devices (for example, icu/sensors).
    2. EmailAddress: Enter an email address for receiving notifications.
  6. Wait for the stack creation to complete. This process might take 5-10 minutes.
  7. After the CloudFormation stack completes, it creates following resources:
    1. An AWS IoT Core rule to capture data from the specified IoTTopic topic and routes it to Kinesis data stream.
    2. A Kinesis data stream for ingesting IoT sensor data.
    3. Two Lambda functions:
      • FilterSensorData: Monitors critical health metrics and sends alerts.
      • AggregateSensorData: Aggregates sensor data in 10 minutes window.
    4. An Amazon DynamoDB table (NotificationTimestamps) to store notification timestamps for rate limiting alerts.
    5. An Amazon SNS topic and subscription to send email notifications for critical patient conditions.
    6. An Amazon Data Firehose delivery stream to deliver processed data to Amazon S3 using Iceberg format.
    7. Amazon S3 buckets to store sensor data.
    8. Amazon Athena and AWS Glue resources for the database and an Iceberg table for querying aggregated data.
    9. AWS Identity and Access Management (IAM) roles and policies to support required permissions for Amazon IoT rules, Lambda functions, and Data Firehose streams.
    10. Amazon CloudWatch log groups to record for Kinesis Firehose activity and Lambda functions.

Solution walkthrough

Now that you’ve deployed the solution, let’s review a functional walkthrough. First, simulate patient vital signs data and send it to AWS IoT Core using the following Python code on your local machine. To run this code successfully, ensure you have the necessary IAM permissions to publish messages to the IoT topic in the AWS account where the solution is deployed.

import boto3
import json
import random
import time
# AWS IoT Data client
iot_data_client = boto3.client(
    'iot-data',
    region_name='us-west-2'
)
# IOT Topic to publish
topic = 'icu/sensors'
# Fixed set of patient IDs
patient_ids = [1, 2, 3, 4, 5, 6, 7, 8, 9, 10]
print("Infinite sensor data simulation...")
try:
    while True:
        for patient_id in patient_ids:
            # Generate sensor data
            message = {
                "patient_id": patient_id,
                "timestamp": int(time.time()),
                "spo2": random.randint(91, 99),
                "heart_rate": random.randint(60, 100),
                "temperature_f": round(random.uniform(97.0, 100.0), 1)
            }
            # Publish to topic
            response = iot_data_client.publish(
                topic=topic,
                qos=1,
                payload=json.dumps(message)
            )
            print(f"Published: {message}")
        # Wait 30 seconds before next round
        print("Sleeping for 30 seconds...\n")
        time.sleep(30)
except KeyboardInterrupt:
    print("\nSimulation stopped by user.")

The following is the format of a sample ICU sensor message produced by the simulator.

{
    "patient_id": 1,
    "timestamp": 1683000000,
    "spo2": 85,
    "heart_rate": 75,
    "temperature_f": 98.6
}

Data is published to the icu/sensors IoT topic every 30 seconds for 10 different patients, creating a continuous stream of ICU patient monitoring data. Messages published to AWS IoT Core are passed to Kinesis Data Streams using the following message routing rule deployed by our solution.

Two Lambda functions consume data from Data Streams concurrently, both using the Lambda event source mapping integration with Kinesis Data Streams.

Event source mapping

Lambda event source mapping automatically triggers Lambda functions in response to data changes from supported event sources like Amazon DynamoDB Streams, Amazon Kinesis Data Streams, Amazon Simple Queue Service (Amazon SQS), Amazon MQ, and Amazon Managed Streaming for Apache Kafka. This serverless integration works by having Lambda poll these sources for new records, which are then processed in configurable batch sizes ranging from 1 to 10,000 records. When new data is detected, Lambda automatically invokes the function synchronously, handling the scaling automatically based on the workload. The service supports at-least-once delivery and provides robust error handling through retry policies and dead-letter queues for failed events. Event source mappings can be fine-tuned through various parameters such as batch windows, maximum record age, and retry attempts, making them highly adaptable to different use cases. This feature is particularly valuable in event-driven architectures, so that customers can focus on business logic while AWS manages the complexities of event processing, scaling, and reliability.

Event source mapping uses tumbling windows and filtering to process and analyze data.

Tumbling windows

Tumbling windows in Lambda event processing enable data aggregation in fixed, non-overlapping time intervals, where each event belongs to exactly one window. This is ideal for time-based analytics and periodic reporting. When combined with event source mapping, this approach allows efficient batch processing of events within defined time periods (for example, 10-minute windows), enabling calculations such as average vital signs or cumulative fluid intake and output while optimizing function invocations and resource usage.

When you configure an event source mapping between Kinesis Data Streams and a Lambda function, use the Tumbling Window Duration setting, which appears in the trigger configuration in the Lambda console. The solution you deployed using the CloudFormation template includes the AggregateSensorData Lambda function, which uses a 10-minute tumbling window configuration. Depending on the volume of messages flowing through the Amazon Kinesis stream, the AggregateSensorData function can be invoked multiple times for each 10-minute window, sequentially, with the following attributes in the event supplied to the function.

  • Window start and end: The beginning and ending timestamps for the current tumbling window.
  • State: An object containing the state returned from the previous window, which is initially empty. The state object can contain up to 1 MB of data.
  • isFinalInvokeForWindow: Indicates if this is the last invocation for the tumbling window. This only occurs once per window period.
  • isWindowTerminatedEarly: A window ends early only if the state exceeds the maximum allowed size of 1 MB.

In a tumbling window, there is a series of Lambda invocations in the following pattern:

AggregateSensorData Lambda code snippet:

def handler(event, context):
    
    state_across_window = event['state']
    # Iterate through each record and decode the base64 data
    for record in event['Records']:
        encoded_data = record['kinesis']['data']
        partition_key = record['kinesis']['partitionKey']
        decoded_bytes = base64.b64decode(encoded_data)
        decoded_str = decoded_bytes.decode('utf-8')
        decoded_json = json.loads(decoded_str)
        # create partition_key attribute if it do not exists in state
        if partition_key not in state_across_window:
            state_across_window[partition_key] = {"min_spo2": decoded_json['spo2'], "max_spo2": decoded_json['spo2'], "avg_spo2": decoded_json['spo2'], "sum_spo2": decoded_json['spo2'], "min_heart_rate": decoded_json['heart_rate'], "max_heart_rate": decoded_json['heart_rate'], "avg_heart_rate": decoded_json['heart_rate'], "sum_heart_rate": decoded_json['heart_rate'], "min_temperature_f": decoded_json['temperature_f'], "max_temperature_f": decoded_json['temperature_f'], "avg_temperature_f": decoded_json['temperature_f'], "sum_temperature_f": decoded_json['temperature_f'], "record_count": 1}
        else:
            min_spo2 = state_across_window[partition_key]['min_spo2'] if state_across_window[partition_key]['min_spo2'] < decoded_json['spo2'] else decoded_json['spo2']
            max_spo2 = state_across_window[partition_key]['max_spo2'] if state_across_window[partition_key]['max_spo2'] > decoded_json['spo2'] else decoded_json['spo2']
            sum_spo2 = state_across_window[partition_key]['sum_spo2'] + decoded_json['spo2']
            min_heart_rate = state_across_window[partition_key]['min_heart_rate'] if state_across_window[partition_key]['min_heart_rate'] < decoded_json['heart_rate'] else decoded_json['heart_rate']
            max_heart_rate = state_across_window[partition_key]['max_heart_rate'] if state_across_window[partition_key]['max_heart_rate'] > decoded_json['heart_rate'] else decoded_json['heart_rate']
            sum_heart_rate = state_across_window[partition_key]['sum_heart_rate'] + decoded_json['heart_rate']
            
            min_temperature_f = state_across_window[partition_key]['min_temperature_f'] if state_across_window[partition_key]['min_temperature_f'] < decoded_json['temperature_f'] else decoded_json['temperature_f']
            max_temperature_f = state_across_window[partition_key]['max_temperature_f'] if state_across_window[partition_key]['max_temperature_f'] > decoded_json['temperature_f'] else decoded_json['temperature_f']
            sum_temperature_f = state_across_window[partition_key]['sum_temperature_f'] + decoded_json['temperature_f']
            
            record_count = state_across_window[partition_key]['record_count'] + 1
            avg_spo2 = sum_spo2/record_count
            avg_heart_rate = sum_heart_rate/record_count
            avg_temperature_f = sum_temperature_f/record_count
            
            state_across_window[partition_key] = {"min_spo2": min_spo2, "max_spo2": max_spo2, "avg_spo2": avg_spo2, "sum_spo2": sum_spo2, "min_heart_rate": min_heart_rate, "max_heart_rate": max_heart_rate, "avg_heart_rate": avg_heart_rate, "sum_heart_rate": sum_heart_rate, "min_temperature_f": min_temperature_f, "max_temperature_f": max_temperature_f, "avg_temperature_f": avg_temperature_f, "sum_temperature_f": sum_temperature_f, "record_count": record_count}
        
    # Determine if the window is final (window end)
    is_final_window = event.get('isFinalInvokeForWindow', False)
    # Determine if the window is terminated (window ended early)
    is_terminated_window = event.get('isWindowTerminatedEarly', False)
    window_start = event['window']['start']
    window_end = event['window']['end']
    if is_final_window or is_terminated_window:
        firehose_client = boto3.client('firehose')
        firehose_stream = os.environ['FIREHOSE_STREAM_NAME']
        for key, value in state_across_window.items():
            value['patient_id'] = key
            value['window_start'] = window_start
            value['window_end'] = window_end
            
            firehose_client.put_record(
                DeliveryStreamName= firehose_stream,
                Record={'Data': json.dumps(value) }
            )
        
        return {
            "state": {},
            "batchItemFailures": []
        }
    else:
        print(f"interim call for window: ws: {window_start} we: {window_end}")
        return {
            "state": state_across_window,
            "batchItemFailures": []
        }
  • The first invocation contains an empty state object in the event. The function returns a state object containing custom attributes that are specific to the custom logic in the aggregation.
  • The second invocation contains the state object provided by the first Lambda invocation. This function returns an updated state object with new aggregated values. Subsequent invocations follow this same sequence. Following is a sample of the aggregated state, which can be supplied to subsequent Lambda invocations within the same 10-minute tumbling window.
{
    "min_spo2": 88,
    "max_spo2": 90,
    "avg_spo2": 89.2,
    "sum_spo2": 625,
    "min_heart_rate": 21,
    "max_heart_rate": 22,
    "avg_heart_rate": 21.1,
    "sum_heart_rate": 148,
    "min_temperature_f": 90,
    "max_temperature_f": 91,
    "avg_temperature_f": 90.1,
    "sum_temperature_f": 631,
    "record_count": 7,
    "patient_id": "44",
    "window_start": "2025-05-29T20:51:00Z",
    "window_end": "2025-05-29T20:52:00Z"
}
  • The final invocation in the tumbling window has the isFinalInvokeForWindow flag set to the true. This contains the state returned by the most recent Lambda invocation. This invocation is responsible for passing aggregated state messages to the Data Firehose stream, which delivers data to the Amazon S3 bucket using Iceberg data format.
  • After the aggregated data is sent to Amazon S3, you can query the data using Athena.
Query: SELECT * FROM "cfdb_<<Database>>"."table_<<Table>>"

Sample result of the preceding Athena query:

Event source mapping with filtering

Lambda event source mapping with filtering optimizes data processing from sources like Amazon Kinesis by applying JSON pattern filtering before function invocation. This is demonstrated in the ICU patient monitoring solution, where the system filters for SpO2 readings from Kinesis Data Streams that are below 90%. Instead of processing all incoming data, the filtering capability is used to selectively processes only critical readings, significantly reducing costs and processing overhead. The solution uses DynamoDB for sophisticated state management, tracking low SpO2 events through a schema combining PatientID and timestamp-based keys within defined monitoring windows.

This state-aware implementation balances clinical urgency with operational efficiency by sending immediate Amazon SNS notifications when critical conditions are first detected while implementing a 15-minute alert suppression window to prevent alert fatigue among healthcare providers. By maintaining state across multiple Lambda invocations, the system helps ensure rapid response to potentially life-threatening situations while minimizing unnecessary notifications for the same patient condition. The integration of Lambda’event filtering, DynamoDB state management, and reliable alert delivery provided by Amazon SNS creates a robust, scalable healthcare monitoring solution that exemplifies how AWS services can be strategically combined to address complex requirements while balancing technical efficiency with clinical effectiveness.

Filter sensor data Lambda code snippet:

sns_client = boto3.client('sns')
dynamodb = boto3.resource('dynamodb')
table_name = os.environ['DYNAMODB_TABLE']
sns_topic_arn = os.environ['SNS_TOPIC_ARN']
table = dynamodb.Table(table_name)
FIFTEEN_MINUTES = 15 * 60  # 15 minutes in seconds
def handler(event, context):
    for record in event['Records']:
        print(f"Aggregated event: {record}")
        encoded_data = record['kinesis']['data']
        partition_key = record['kinesis']['partitionKey']
        decoded_bytes = base64.b64decode(encoded_data)
        decoded_str = decoded_bytes.decode('utf-8')
        # Check last notification timestamp from DynamoDB
        try:
            response = table.get_item(Key={'partition_key': partition_key})
            item = response.get('Item')
            now = int(time.time())
            if item:
                last_sent = item.get('timestamp', 0)
                if now - last_sent < FIFTEEN_MINUTES:
                    print(f"Notification for {partition_key} skipped (sent recently)")
                    continue
            # Send SNS Notification
            sns_response = sns_client.publish(
                TopicArn=sns_topic_arn,
                Message=f"Patient SpO2 below 90 percentage event information: {decoded_str}",
                Subject=f"Low SpO2 detected for patient ID {partition_key}"
            )
            print("Message sent to SNS! MessageId:", sns_response['MessageId'])
            # Update DynamoDB with current timestamp and TTL
            table.put_item(Item={
                'partition_key': partition_key,
                'timestamp': now,
                'ttl': now + FIFTEEN_MINUTES + 60  # Add extra buffer to TTL
            })
        except Exception as e:
            print("Error processing event:", e)
            return {
                'statusCode': 500,
                'body': json.dumps('Error processing event')
            }
    return {
        'statusCode': 200,
        'body': {}
    }

To generate an alert notification through the deployed solution, update the preceding simulator code by setting the SpO2 value to less than 90 and run it again. Within 1 minute, you should receive an alert notification at the email address you provided during stack creation. The following image is an example of an alert notification generated by the deployed solution.

Clean up

To avoid ongoing costs after completing this tutorial, delete the CloudFormation stack that you deployed earlier in this post. This will remove most of the AWS resources created for this solution. You might need to manually delete objects created in Amazon S3, because CloudFormation won’t remove non-empty buckets during stack deletion.

Conclusion

As demonstrated in this post, you can build a serverless real-time analytics pipeline for healthcare monitoring by using AWS IoT Core, Amazon S3 buckets with iceberg format, and Amazon Kinesis Data Streams integration with AWS Lambda event source mapping. This architectural approach eliminates the need for complex code while enabling rapid critical patient care alerts and data aggregation for analysis using Lambda. The solution is particularly valuable for healthcare organizations looking to modernize their patient monitoring systems with real-time capabilities. The architecture can be extended to handle various medical devices and sensor data streams, making it adaptable for different healthcare monitoring scenarios. This post presents one implementation approach, and organizations adopting this solution should ensure the architecture and code meets their specific application performance, security, privacy, and regulatory compliance needs.

If this post helps you or inspires you to solve a problem, we would love to hear about it!


About the authors

Nihar Sheth

Nihar Sheth

Nihar is a Senior Product Manager on the AWS Lambda team at Amazon Web Services. He is passionate about developing intuitive product experiences that solve complex customer problems and enable customers to achieve their business goals.

Pratik Patel

Pratik Patel

Pratik is Sr Technical Account Manager and streaming analytics specialist. He works with AWS customers and provides ongoing support and technical guidance to help plan and build solutions using best practices and proactively helps in keeping customers’ AWS environments operationally healthy.

Priyanka Chaudhary

Priyanka Chaudhary

Priyanka is Senior Solutions Architect at AWS. She is specialized in data lake and analytics services and helps many customers in this area. As a Solutions Architect, she plays a crucial role in guiding strategic customers through their cloud journey by designing scalable and secure cloud solutions. Outside of work, she loves spending time with friends and family, watching movies, and traveling.

Set up custom domains in Amazon Connect hosted with M365 Exchange Online or Google Workspace

Post Syndicated from Zip Zieper original https://aws.amazon.com/blogs/messaging-and-targeting/set-up-custom-domains-in-amazon-connect-hosted-with-m365-exchange-online-or-google-workspace/

Amazon Connect Email provides built-in capabilities that make it straightforward to prioritize, assign, and automate the resolution of customer service emails, improving customer satisfaction and agent productivity. With Amazon Connect Email, you can receive and respond to emails sent by customers to business addresses or submitted through web forms on your website or mobile app. You can configure auto-responses, prioritize emails, create or update cases, and route emails to the best available agent when agent assistance is required. Additionally, these capabilities work seamlessly with Amazon Connect outbound campaigns, helping you deliver proactive and personalized email communications.

Amazon Connect Email integrates with Amazon Simple Email Service to send, receive, and monitor emails for content marked as spam or containing viruses, delivery success rates, and sender reputation results.

This post guides you through setting up email in Amazon Connect by routing emails from your email server (Microsoft 365 or Google Workspace) to Amazon Simple Email Service (Amazon SES) SMTP endpoints using a custom email domain onboarded to Amazon SES. By configuring Amazon Connect with your custom email domain in Amazon SES, you can create a unified communication hub that enhances customer experience while simplifying agent workflows. The result is a more responsive, efficient contact center that meets customers where they are, whether they prefer speaking, chatting, or sending emails.

Use case overview

AnyCompany has invested heavily in its email infrastructure over the years, developing a robust and centralized email server that manages both internal and external email traffic. This unified system has become an integral part of their operations, streamlining communication across departments and with customers. AnyCompany has also established a public support email address that has gained significant recognition and trust among their customer base. This email address, featured prominently in all their product documentation, marketing materials, and customer communications, has become a cornerstone of their brand identity in customer support.

Now, AnyCompany faces the challenge of enhancing their customer support process by implementing an automated acknowledgment system for incoming support emails. However, they want to maintain their existing email setup due to its deep integration with internal workflows and the substantial investment it represents. Additionally, preserving their well-known support email address is crucial to protect the brand equity they’ve built over years of customer interactions.

By integrating Amazon Connect with their current email server, AnyCompany can create a seamless solution that addresses these complex requirements. With this integration, customers can continue sending emails to the familiar public support address (for example, [email protected]), maintaining consistency in their customer experience. When new emails are received, Amazon Connect can trigger automated acknowledgment messages, providing immediate assurance to customers that their inquiries have been received and are being processed.

This approach offers multiple benefits. It improves customer satisfaction by providing prompt responses and reduces the volume of follow-up emails. It also preserves AnyCompany’s significant investment in their existing email infrastructure, so they can continue using the centralized system for both internal and external communications. Perhaps most importantly, it maintains the brand recognition associated with their long-standing support email address, so customers can continue to use the contact point they’ve grown to trust over the years.

Solution overview

This post provides a contact center email solution with the following benefits:

  • Customers continue to send emails to your custom domain
  • Emails are routed through your primary email server to Amazon Connect (via Amazon SES)
  • Agents receive and respond to emails within the Amazon Connect agent workspace
  • Customers receive agent responses from your custom domain (via Amazon SES)

This solution involves three main steps:

  1. Configure Microsoft 365 or Google Workspace to route emails to Amazon Connect
  2. Verify your custom domain in Amazon SES to enable sending emails
  3. Onboard your email address in Amazon Connect to handle customer communications

Prerequisites

Before you begin, make sure you have the following prerequisites:

  • Administrative access to modify your custom email domain’s DNS settings.
    • Note – modifying MX records can impact email receiving for your primary domain (example.com). It is highly recommended to create a subdomain (for example, testing.example.com) for testing to avoid impacting any email receiving on your primary domain or use the provided email domain that comes with the Amazon Connect instance (for example, @<instance-alias>.email.connect.aws).
  • Administrative access to modify your Microsoft 365 Exchange Online or Google Workspace Gmail configuration.
  • AWS Identity and Access Management (IAM) access to Amazon SES and Amazon Connect on your AWS Management Console.
  • An existing user in Amazon Connect with access to managing email flows, channels, and routing. For example, CallCenterManager can be used to perform actions related to user management, metrics, and routing. Or you can create a user with a custom scoped-down security profile.
  • When setting up Amazon Simple Email Service for use with Amazon Connect your SES account will be in the sandbox mode, which works well for testing. You will need to request Amazon SES production access before you can fully utilize Amazon SES with Amazon Connect.

Configure Amazon SES

Part of creating a domain identity is configuring its DKIM-based verification. DomainKeys Identified Mail (DKIM) is an email authentication method that Amazon SES uses to verify domain ownership, and receiving mail servers use to validate email authenticity. To learn more, refer to Creating a domain identity.

Complete the following steps to configure your domain identity in Amazon SES:

  1. Open your AWS console and choose the AWS Region where your Amazon Connect instance is deployed.
  2. On the Amazon SES console, choose Identities under Configuration in the navigation pane.
  3. Choose Create identity and provide the following information:
    1. Choose Domain as the identity type.
    2. Enter your custom email domain name.
    3. Enable Use a custom MAIL FROM domain.
    4. Set MAIL FROM domain to feedback.
    5. Set Behavior on MX failure to Use default MAIL FROM domain.
  4. For DKIM verification, provide the following information (unless instructed otherwise):
    1. Choose Easy DKIM under Advanced DKIM settings.
    2. Choose RSA_2048_BIT for DKIM signing key length.
    3. Enable Publish DNS records to Route53 if applicable.
    4. Enable DKIM signatures.
  5. Choose Create identity.

Amazon SES will generate DNS records needed to verify the domain, including:

  • DKIM CNAME records
  • Custom MAIL FROM domain MX and TXT records
  • DMARC TXT records

If the domain is hosted in Route 53, Amazon SES provides an option to automatically Publish DNS records to Route53. When your domain is hosted with Route 53, SES domain verification typically completes within a few minutes. You will see the status Verification pending, followed by Verified.

If the domain is not hosted in Route53, Amazon SES will present individual copy buttons per record as well as a CSV file download option. These records must be added to your DNS so Amazon SES can verify the domain.

After your externally managed DNS has been updated, return to the Amazon SES console and confirm that the identity status has changed to Verified. The time to complete this step is highly variable. You can choose to configure DKIM by using either Easy DKIM or Bring Your Own DKIM (BYODKIM), and depending on your choice, you will have to configure the signing key length of the private key. For detailed steps, refer to Creating a domain identity.

When you first setup Amazon SES, your account is placed in the SES sandbox which we use to prevent unauthorized or unintended sending. While in sandbox mode, you can only send mail to email addresses and domains you verify. After you receive Amazon SES production access for your custom domain, you can send and receive email to and from a valid email address without verification. For more information about the Amazon SES sandbox, refer to Request production access (Moving out of the Amazon SES sandbox).

For setup and testing purposes, complete the following steps to configure an email identity in Amazon SES:

  1. On the Amazon SES console, choose Identities under Configuration in the navigation pane.
  2. Choose Create identity and choose Email Address.
  3. Enter your work email address (you will need access to the inbox to verify ownership). This is the email address that Amazon Connect and Amazon SES will use to send and receive email while your SES account is in the sandbox.
  4. Click Create identity.
  5. Check your email inbox and click the link to verify this is an email address you control.

Configure Amazon Connect

Complete the following steps to configure Amazon Connect:

  1. On the Amazon Connect console, open your instance by clicking on Instance alias.
  2. Under Channels and communications, choose Email.
  3. Choose Add domain.
  4. Choose the domain you verified in Amazon SES.
  5. In your instance, choose Email addresses under Channels.
  6. Choose Create email address and provide the following information:
    1. Create an email address with the same name and domain as the inbound address your customers will use ([email protected]).
    2. Provide a friendly sender name that will appear in customer inboxes.
    3. Create a new flow or attach an existing flow to the custom domain email address (this flow will route inbound emails).
    4. Choose Save.
  7. Configure Outbound email configuration in your outbound queue:
    1. For Default email address, provide the email address you created earlier.
    2. For Outbound email flow, provide the email flow for outbound emails (this flow will route outbound emails).
    3. Choose Save.

Configure Microsoft 365 Exchange or Google Workspace

In this section, we provide step-by-step guidance to configure your primary email service with a rule (Microsoft) or route (Google) that sends inbound email addressed to a specific address(s) to Amazon Connect.

Option A: Microsoft 365 Exchange configuration

Complete the following steps to configure Microsoft 365 Exchange:

  1. Find the email receiving endpoint for your Region. For example, inbound-smtp.us-west-2.amazonaws.com.
  2. Create a connector in Exchange:
    1. Navigate to the Exchange admin center.
    2. Under Mail flow, choose Connectors.
    3. Choose Add a connector.
    4. Set Connection from to Office 365
    5. Set Connection to to Your organization’s email server.
    6. Choose Next.
    7. Name the connector to identify the Region.
    8. Choose Next.
    9. For Use of connector, select Only when I have a transport rule set up that redirects messages to this connector.
    10. For Routing, enter the SES email receiving endpoint.
    11. Choose the plus sign, then choose Next.
    12. For Security restrictions, select Always use Transport Layer Security (TLS) to secure the connection.
    13. Follow your internal process for this step. In this example, we select Any digital certificate, including self-signed certificates.
    14. Choose Next.
    15. For Validation email, enter a valid email address currently used in your Amazon Connect instance.
    16. Choose the plus sign, then choose Next.
      This will send a test email address to that email address. No action needs to be taken with the test email. You should see the email validated and receive the validation test email in the agent workspace.
    17. Review your connector configuration and choose Create connector.

Validate that the connector status is set to On, then proceed to the next steps.

  1. Create a mail flow rule to send your inbound email to Amazon Connect:
    1. Under Mail flow, choose Rules.
    2. Choose Add a rule¸ then choose Create a new rule.
    3. Name the rule.
    4. Set conditions to apply if the recipient is this person and choose the email address for Amazon Connect.
    5. Set the action to Redirect the message to and the following connector and choose your new connector.
    6. Choose Next.
    7. Set Rule mode to Enforce.
    8. Activate the rule immediately by specifying the current time.
    9. Set Match sender address in message to Header or envelope.
    10. Choose Next.
    11. Review your rule configuration and choose Finish.

After you confirm your rule is enabled, you can test your configuration.

Option B: Google Workspace Gmail configuration

Complete the following steps to configure with Google Workspace:

  1. Log into your Google Workspace admin account.
  2. Navigate to Gmail.
  3. Choose Hosts and choose Add Route.
  4. Configure the mail route:
    1. Provide a name indicating the Region.
    2. Enter the SES email receiving endpoint and port 25.
    3. Enable security options:
      1. Select Require mail to be transmitted via a secure (TLS) connection.
      2. Select Require CA signed certificate.
      3. Select Validate certificate hostname.
    4. Choose Test TLS connection.
    5. If the connection is successful, choose SAVE.
  5. Configure default routing:
    1. Navigate to Default routing and choose Configure.
    2. Enter the email address that should route to Amazon Connect.
    3. Change the route to the mail route you created.
    4. Select Perform this action on non-recognized and recognized addresses.
    5. Save and confirm the route is enabled.

Test your configuration

After you have completed the appropriate steps above, test both inbound (to Amazon Connect) and outbound (from Amazon Connect) message-flows.

Test inbound (to Amazon Connect)

Test your inbound configuration:

  1. Open your email application.
  2. Send a test email to the email address you configured to be sent to Amazon Connect.
  3. In the Amazon Connect agent workspace, accept the incoming email.
  4. Confirm the email received in your agent workspace matches the email address you configured to be sent to Amazon Connect.

Test outbound (to external recipient from Amazon Connect)

Test your outbound configuration:

  1. Log in to your Amazon Connect instance.
  2. Choose New email.
  3. Enter To address (use your work email address), Subject & Body.
    1. Alternatively, To address (use your work email address) and choose a Template.
  4. Click Send.
  5. Check your work email inbox for the message. Verify the email’s From address is the email address you configured to be sent from Amazon Connect.

Request Amazon SES production access

Once you have successfully tested email receiving and sending within Amazon Connect, request Amazon SES production access (see Moving out of the Amazon SES sandbox) in the Amazon SES Developer Guide. Importantly, you will not be able to send email from your domain via Amazon Connect until your account is removed from the SES sandbox.

Conclusion

In this post, we showed how to configure Amazon Connect to handle emails using your custom domain through Microsoft 365 or Google Workspace. This setup provides a seamless email experience for your customers while giving your agents the powerful tools available in the Amazon Connect agent workspace.

To get started with Amazon Connect Email, refer to the Amazon Connect Administrator Guide. For hands-on learners, the Amazon Connect Email Enablement Workshop provides guidance and exercises to configure Amazon Connect Email, set up email queues and routing rules, and discusses best practices for delivering exceptional email-based customer service.

Additional resources

For additional guidance and information, refer to the following resources:


About the authors

How to configure and verify ACM certificates with trust stores

Post Syndicated from Chris Morris original https://aws.amazon.com/blogs/security/how-to-configure-and-verify-acm-certificates-with-trust-stores/

In this post, we show how to configure customer trust stores to work with public certificates issued through AWS Certificate Manager (ACM). Organizations can encounter challenges when configuring trust stores for ACM certificates and incorrect trust store configuration can lead to SSL/TLS errors and application downtime. While most modern web browsers and operating systems trust ACM certificates by default, understanding how this trust is established and verifying proper configuration is important for IT professionals and developers. We also describe the relationship between public certificates issued through ACM and Amazon Trust Services. Whether you’re developing applications that connect to endpoints using ACM certificates or managing systems with customer trust stores that need to trust ACM certificates, this guide will provide you with insight regarding ACM certificate trust.

Background

ACM is a managed service that you can use to provision, manage, and deploy public and private SSL/TLS certificates. When you visit a website over HTTPS that has an ACM certificate, most modern web browsers will show a Connection is secure message in the address bar. This indicates that the web browser trusted the certificate. ACM certificates are trusted by popular browsers such as Chrome, Firefox, and Safari because they are issued by Amazon Trust Services, a public certificate authority (CA) managed by Amazon, whose root CA certificates are included by default in most web browsers’ and operating systems’ trust stores.

What is a trust store?

Web browsers, devices, and applications trust a collection of certificates known as CA certificates. These collections of CA certificates are called trust stores. Most often, the CA certificates in a trust store are root CA certificates. Root CA certificates are CA certificates that act as the foundation of trust. It’s best practice that root CAs issue intermediate CA certificates, which then issue end-entity certificates to minimize interaction with the root CA. When navigating to a website protected with HTTPS using a web browser, the website will present the end-entity certificate and the certificate chain. The certificate chain is a series of certificates, each issued by the next, leading back to a root CA certificate. The web browser will then check the end-entity certificate. It will make sure it’s derived from a root certificate that is in its trust store. It is important to note that trust store configurations can vary depending on the web browser, device or application.

Amazon Trust Services

Amazon Trust Services is a publicly trusted CA that is managed by Amazon. Amazon Trust Services root CA certificates are included in the trust stores of most web browsers and operating systems. As shown in Figure 1, when you request a public ACM certificate through DNS, Email, or HTTP validation, it will be issued by one of the multiple intermediate CAs that Amazon manages. These intermediate CAs are issued by one of the five Amazon Trust Services root CAs. Therefore, by trusting the Amazon Trust Services root CAs, you will be trusting ACM certificates. It’s important to note that ACM uses a dynamic intermediate CA model. This means you cannot predict which specific intermediate CA will issue an ACM certificate. The issuing intermediate CA is selected dynamically from a group of intermediate CAs at the time of certificate issuance. This means that the intermediate CA that issues ACM certificates is non-deterministic. In summary, we recommend customer trust stores include the five Amazon Trust Services root CA certificates. This includes Amazon Root CA 1, Amazon Root CA 2, Amazon Root CA 3, Amazon Root CA 4 and Starfield Services Root Certificate Authority – G2.

Figure 1 – ACM certificate chain

Figure 1 – ACM certificate chain

Best practices

To help establish reliable HTTPS connections to endpoints using ACM certificates, we recommend that your trust stores include the five Amazon root CAs.

Distinguished name of Amazon root CA SHA-256 hash of subject public key information URL to root CA certificate in DER or PEM format
CN=Amazon Root CA
1,O=Amazon,C=US
fbe3018031f9586bcbf41727e417b7d1c45c2f47f93be372a17b96b50757d5a2 DER, PEM
CN=Amazon Root CA
2,O=Amazon,C=US
7f4296fc5b6a4e3b35d3c369623e364ab1af381d8fa7121533c9d6c633ea2461 DER, PEM
CN=Amazon Root CA
3,O=Amazon,C=US
36abc32656acfc645c61b71613c4bf21c787f5cabbee48348d58597803d7abc9 DER, PEM
CN=Amazon Root CA
4,O=Amazon,C=US
f7ecded5c66047d28ed6466b543c40e0743abe81d109254dcf845d4c2c7853c5 DER, PEM
CN=Starfield Services Root Certificate Authority – G2,O=Starfield Technologies\, Inc.,L=Scottsdale,ST=Arizona,C=US 2b071c59a0a0ae76b0eadb2bad23bad4580b69c3601b630c2eaf0613afa83f92 DER, PEM

Adding the five Amazon root CAs provide maximum compatibility for trusting ACM certificates. If you must use certificate pinning in your application, we recommend that you pin to the public key of the mentioned root CAs.

While addressing the best practices, it is important to review how trust stores should not be configured.

Don’t limit your trust stores to only the intermediate CA certificates that issue ACM certificates. Examples of such intermediate CAs include Amazon RSA 2048 M01, Amazon RSA 2048 M02, Amazon RSA 2048 M03. Adding only these intermediate CA certificates to your trust store will introduce risk to your application. This is because of the dynamic intermediate CA (ICA) model. When an ACM certificate is issued or when it’s renewed, it will be from one of the many intermediate CAs. Furthermore, they are non-deterministic. If an ACM certificate was first issued by Amazon RSA 2048 M01, there is no guarantee that it will renew from that same intermediate CA.

In summary, here are the best practices for trusting ACM certificates.

How do I verify that the Amazon root CAs are in my trust store?

As mentioned in the previous section, most modern web browsers and operating systems already include the five Amazon root CAs in their respective trust stores by default. It’s still recommended to verify that the Amazon root CAs are installed correctly. It’s important to note that many applications have different trust store locations. For example, an application might use the Windows trust store location—Trusted Root Certification Authorities—as its trust store or it might use a PEM trust store in a custom directory. This is why we recommend that you review your application’s trust store documentation.

To verify, check your system’s trust store for existing Amazon root CA certificates. If they are not present, you can proceed with adding the five Amazon root CA certificates.

Windows: Check for the Amazon root CAs in Windows operating systems (GUI)

  1. Press Windows + R, enter certmgr.msc , then press Enter.
  2. Go to Trusted Root Certification Authorities and choose Certificates.
Figure 2: Windows certificate store: Trusted Root Certification Authorities

Figure 2: Windows certificate store: Trusted Root Certification Authorities

Check for the Amazon root CAs in Windows operating systems (CLI)

You can use Powershell to check for the Amazon root CAs. Use the certutil command.

  • Open Windows Powershell and use the following certutil commands. These will search for the five Amazon root CAs.
> certutil -store AuthRoot | findstr /i "Amazon" 
Issuer: CN=Amazon Root CA 4, O=Amazon, C=US 
Subject: CN=Amazon Root CA 4, O=Amazon, C=US 
Issuer: CN=Amazon Root CA 1, O=Amazon, C=US 
Subject: CN=Amazon Root CA 1, O=Amazon, C=US 
Issuer: CN=Amazon Root CA 2, O=Amazon, C=US 
Subject: CN=Amazon Root CA 2, O=Amazon, C=US 
Issuer: CN=Amazon Root CA 3, O=Amazon, C=US 
Subject: CN=Amazon Root CA 3, O=Amazon, C=US

> certutil -store AuthRoot | findstr /i "Starfield Services Root Certificate Authority - G2" 
Issuer: CN=Starfield Services Root Certificate Authority - G2, O=Starfield Technologies, Inc., L=Scottsdale, S=Arizona, C=US
Subject: CN=Starfield Services Root Certificate Authority - G2, O=Starfield Technologies, Inc., L=Scottsdale, S=Arizona, C=US

Add Amazon root CAs to the default trust store using the UI

Download each Amazon Trust Services root CA. You can select the DER or PEM versions.

  1. Open Certmgr: Press Windows + R, enter certmgr.msc, and press Enter.
  2. Add to the trusted root:
    1. Choose Trusted Root Certification Authorities.
    2. Right-click Certificates.
    3. Select All Tasks and choose Import.
    4. Follow the Certificate Import Wizard:
      1. Choose Next.
      2. Browse to the root CA certificate file location. You might need to select All Files(*.*) to view the root CA certificate files.
      3. Select Place all certificates in the following store.
      4. Verify Trusted Root Certification Authorities is selected and choose Next.
      5. Choose Finish.

Add Amazon root CAs to the default trust store using the CLI

  1. Download each Amazon Trust Services root CA. You can select the DER or PEM versions.
  2. In Powershell, add a CA certificate to AuthRoot using certutil.
    > certutil -addstore AuthRoot AmazonRootCA1.cer
  3. In Powershell, verify that the certificate has been added.
    > certutil -store AuthRoot | findstr /i "Amazon"

Amazon Linux 2023: Check for the Amazon root CAs in default trust store

The following is the default location for the system trust store in Amazon Linux 2023:

/etc/pki/tls/certs/ca-bundle.crt

1. Using OpenSSL, search for Amazon root CA certificates in the ca-bundle.crt bundle:

openssl crl2pkcs7 -nocrl -certfile /etc/pki/tls/certs/ca-bundle.crt | openssl pkcs7 -print_certs -noout | grep -i "Amazon\|Starfield Services" 

subject=C=US, O=Amazon, CN=Amazon Root CA 1 
issuer=C=US, O=Amazon, CN=Amazon Root CA 1 
subject=C=US, O=Amazon, CN=Amazon Root CA 2 
issuer=C=US, O=Amazon, CN=Amazon Root CA 2 
subject=C=US, O=Amazon, CN=Amazon Root CA 3 
issuer=C=US, O=Amazon, CN=Amazon Root CA 3 
subject=C=US, O=Amazon, CN=Amazon Root CA 4 
issuer=C=US, O=Amazon, CN=Amazon Root CA 4 
subject=C=US, ST=Arizona, L=Scottsdale, O=Starfield Technologies, Inc., CN=Starfield Services Root Certificate Authority - G2 
issuer=C=US, ST=Arizona, L=Scottsdale, O=Starfield Technologies, Inc., CN=Starfield Services Root Certificate Authority - G2

To add the Amazon root CAs to the default trust store

1. Navigate to the following directory for adding CA certificates
$ cd /etc/pki/ca-trust/source/anchors/

2. Using cURL, download each Amazon Trust Services root CA in the preceding folder. Do this for each of the Amazon root CAs replacing the name of the PEM file as needed.

$ sudo curl -O
https://www.amazontrust.com/repository/AmazonRootCA1.pem

3. Add the root CAs by updating the system trust store.
$ sudo update-ca-trust extract

4. Verify that the bundle has been updated with OpenSSL.
$ openssl crl2pkcs7 -nocrl -certfile /etc/pki/tls/certs/ca-bundle.crt | openssl pkcs7 -print_certs -noout | grep -i "Amazon\|Starfield Services"

Java: Check for the Amazon root CAs in a Java trust store (Java Keystore)

Many custom Java applications use Java Keystore (JKS) as a trust store. You can use the keytool CLI tool to verify if the Amazon root CAs exist in your JKS trust store.

keytool -list -keystore custom_truststore.jks -storepass mypassword

Keystore type: PKCS12
Keystore provider: SUN

Your keystore contains 5 entries

amazonrootca1, Jun 27, 2025, trustedCertEntry, Certificate fingerprint (SHA-256): 8E:CD:E6:88:4F:3D:87:B1:12:5B:A3:1A:C3:FC:B1:3D:70:16:DE:7F:57:CC:90:4F:E1:CB:97:C6:AE:98:19:6E 
amazonrootca2, Jun 27, 2025, trustedCertEntry, Certificate fingerprint (SHA-256): 1B:A5:B2:AA:8C:65:40:1A:82:96:01:18:F8:0B:EC:4F:62:30:4D:83:CE:C4:71:3A:19:C3:9C:01:1E:A4:6D:B4 
amazonrootca3, Jun 27, 2025, trustedCertEntry, Certificate fingerprint (SHA-256): 18:CE:6C:FE:7B:F1:4E:60:B2:E3:47:B8:DF:E8:68:CB:31:D0:2E:BB:3A:DA:27:15:69:F5:03:43:B4:6D:B3:A4 
amazonrootca4, Jun 27, 2025, trustedCertEntry, Certificate fingerprint (SHA-256): E3:5D:28:41:9E:D0:20:25:CF:A6:90:38:CD:62:39:62:45:8D:A5:C6:95:FB:DE:A3:C2:2B:0B:FB:25:89:70:92 
starfieldg2, Jun 27, 2025, trustedCertEntry, Certificate fingerprint (SHA-256): 56:8D:69:05:A2:C8:87:08:A4:B3:02:51:90:ED:CF:ED:B1:97:4A:60:6A:13:C6:E5:29:0F:CB:2A:E6:3E:DA:B5

The output should show the Amazon root CAs listed as “trustedCertEntry” with those exact certificate fingerprints.

To add the Amazon root CAs to a Java trust store (Java Keytool)

1. Download each Amazon Trust Services root CA in PEM or DER format. Use the PowerShell command Invoke-WebRequest if you’re using Windows, or use cURL if you’re using a Linux-based operating system or MacOS.

> Invoke-WebRequest -Uri "https://www.amazontrust.com/repository/AmazonRootCA1.pem" -OutFile "AmazonRootCA1.pem"

$ curl -O https://www.amazontrust.com/repository/AmazonRootCA1.pem

2. Import the Amazon root CAs to the trust store—custom_truststore.jks. Replace changeit with your JKS password. Do this command for each of the Amazon root CAs, replacing the name of the root CA as needed.

$ keytool -importcert -alias "AmazonRootCA1" -file "AmazonRootCA1.pem" -keystore custom_truststore.jks -storepass changeit -trustcacerts -noprompt

Test your trust store configuration

After you have set up your trust store with the five Amazon root CA certificates, you can perform tests to confirm that the installed root CAs are correctly providing trust. Remember that your custom application might be sourcing its trust from a store other than the stores mentioned in this article. For custom applications, we recommend checking your testing documentation.

PEM

For operating systems or applications that use PEM certificate bundles, such as Amazon Linux 2023, you can use OpenSSL or cURL to test. For additional test URLs, see the Amazon Trust Services website. Replace CAbundle.pem with your certificate bundle.

$ openssl s_client -connect valid.rootca1.demo.amazontrust.com:443 -CAfile CAbundle.pem

$ curl -iv --cacert CAbundle.pem https://valid.rootca1.demo.amazontrust.com

Windows

Because Windows doesn’t use PEM certificate bundles, but a trust store in certmgr called Trusted Root Certification Authorities, you can use PowerShell to test.

1. Copy the following PowerShell script and save it in a file named ssl-connect.ps1.


param (
[string]$url = "https://valid.rootca1.demo.amazontrust.com"
)

$sslStream = $null
$tcpClient = $null

try {
$uri = [System.Uri]$url
$hostname = $uri.Host
$port = if ($uri.Port -eq -1) { 443 } else { $uri.Port }

# Connect to the server
$tcpClient = New-Object System.Net.Sockets.TcpClient
$tcpClient.Connect($hostname, $port)

# Define the certificate validation callback
$callback = {
param($sender, $certificate, $chain, $sslPolicyErrors)

Write-Host "Server Certificate:`nSubject : $($certificate.Subject)`nIssuer : $($certificate.Issuer)`n"

Write-Host "Certificate Chain:"
foreach ($c in $chain.ChainElements) {
Write-Host ("Subject : {0}`nIssuer : {1}`nThumbprint : {2}`n" -f
$c.Certificate.Subject,
$c.Certificate.Issuer,
$c.Certificate.Thumbprint)
}


if ($sslPolicyErrors -eq 'None') {
Write-Host "Certificate is valid and trusted."
} else {
Write-Host "Certificate error(s): $sslPolicyErrors"
}

return $true
}

# Create the SSL stream using the callback
$sslStream = New-Object System.Net.Security.SslStream($tcpClient.GetStream(), $false, $callback)

# Initiate TLS handshake
$sslStream.AuthenticateAsClient($hostname)
}
catch {
Write-Host "ERROR: $($_.Exception.Message)"
}
finally {
if ($sslStream) { $sslStream.Dispose() }
if ($tcpClient) { $tcpClient.Close() }
}

2. Run the PowerShell script with the following command:

  • > .\ssl-connect.ps1

You can test with the other test URLs by passing them in -url:

  • > .\ssl-connect.ps1 -url https://s3.amazonaws.com

3. After running the command, you should see the subject and issuer of the end-entity certificate and the full trust chain, including the intermediate CA and root CA. If the command returns Certificate is valid and trusted, the certificate is trusted. If it returns an error with Certificate error, the error should tell you what went wrong.

Java

To test your Java applications that use JKS as a trust store, you can make HTTPS connections to endpoints that use Amazon Trust Services certificates.

1. Copy the Java code and name the file SSLTester.java.

  • In the code, you can replace the urls variable with additional URLs to test HTTPS. See the Amazon Trust Services website for additional test URLs.
  • Update your_keystore.jks and your password with your JKS file path and password.
import javax.net.ssl.SSLContext; 
import javax.net.ssl.TrustManagerFactory; 
import java.io.FileInputStream; 
import java.net.URL; 
import java.security.KeyStore;
import java.security.cert.Certificate; 
import java.security.cert.X509Certificate; 

public class SSLTester {
     public static void main(String[] args) {
         // Enable revocation checking
         System.setProperty("com.sun.net.ssl.checkRevocation", "true");
         System.setProperty("com.sun.security.enableCRLDP", "true");   
         System.setProperty("com.sun.security.enableAIAcaIssuer", "true");
         // Define your HTTPS URLs here
         String[] urls = {
              "https://valid.rootca1.demo.amazontrust.com/",  // Use an Amazon Trust Services Valid test URL (Example: https://valid.rootca1.demo.amazontrust.com/)
              "https://revoked.rootca1.demo.amazontrust.com/", // Use an Amazon Trust Services Revoked test URL (Example: https://revoked.rootca1.demo.amazontrust.com/)
              "https://expired.rootca1.demo.amazontrust.com/", // Use an Amazon Trust Services Expired test URL (Example: https://expired.rootca1.demo.amazontrust.com/)
              "https://ec2.amazonaws.com" // AWS Service Endpoint
		  };
          String keystorePath = "your_keystore.jks"; // Define your .jks file
          String keystorePassword = "your password"; // Pass your keystore password

          try {
             // Load the JKS
             KeyStore trustStore = KeyStore.getInstance("JKS");
             FileInputStream fis = new FileInputStream(keystorePath);
             trustStore.load(fis, keystorePassword.toCharArray());
             fis.close();

             // Initialize TrustManagerFactory with JKS
             TrustManagerFactory tmf = 
TrustManagerFactory.getInstance(TrustManagerFactory.getDefaultAlgorithm());
             tmf.init(trustStore);
            // Initialize SSLContext
            SSLContext sslContext =
SSLContext.getInstance("TLS");
             sslContext.init(null, tmf.getTrustManagers(), null);

             // Test SSL connections to URLs
             for (String urlStr : urls) {
                 System.out.println("Testing URL: " + urlStr);
                 try {
                     URL url = new URL(urlStr);
                     javax.net.ssl.HttpsURLConnection conn = (javax.net.ssl.HttpsURLConnection) url.openConnection();                    conn.setSSLSocketFactory(sslContext.getSocketFactory());
                     conn.connect();

                     // Get server certificate
                     Certificate[] certs = 
conn.getServerCertificates();
                     for (Certificate cert : certs) {
                         if (cert instanceof X509Certificate) {
                             X509Certificate x509Cert = (X509Certificate) cert;
                             System.out.println("Certificate: " + x509Cert.getSubjectDN());
                         }
                     }
                     System.out.println("Connection successful for " + urlStr);
                     conn.disconnect();
                 } catch (Exception e) {
                     System.err.println("Failed for " + urlStr + ": " + e.getMessage());
                 }
             }
         } catch (Exception e) {
             e.printStackTrace();
         }
     }
 }

2. After you save the file, compile it and run.

javac SSLTester.java
java SSLTester.java

3. Check the output after it’s finished running.

  • For Valid URLs, you should see Connection successful:
  • Connection successful for https://valid.rootca1.demo.amazontrust.com/

  • For Revoked URLs, you should see Certificate has been revoked:
  • failed: java.security.cert.CertPathValidatorException: Certificate has been revoked, reason: UNSPECIFIED

  • For Expired URLs, you should see Validity check failed:

Failed for https://expired.rootca1.demo.amazontrust.com/: PKIX path validation failed: java.security.cert.CertPathValidatorException: validity check failed

Conclusion

When your web browser, device, or application performs HTTPS connections, it validates the certificate presented by the server using its trust store. A trust store is a collection of trusted CA certificates, primarily consisting of root CA certificates. When trusting endpoints using public certificates issued through ACM, best practice recommends installing the five Amazon Trust Services root CA certificates into your trust store. Be aware that trusting only the Amazon Trust Services intermediate CA certificates, such as Amazon RSA 2048 M01 and Amazon RSA 2048 M02, increases your application’s risk for outages. This is because of the non-deterministic nature of the dynamic intermediate CA (ICA) model. It’s worth noting that trust store configurations can vary across different applications. Furthermore, applications can also source their trust store from different locations. For example, you can have a Java application hosted on a Windows-based operating system that sources its trust store from a Java Keystore (JKS) file rather than the default Windows trust store location Trusted Root Certification Authorities. This means that you should thoroughly test your application after installing the Amazon Trust Services root CA certificates in your trust store. This will help to sustain reliable HTTPS connections to endpoints using ACM certificates.


If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Chris Morris

Chris Morris

Chris is a Sr. Cloud Support Engineer at AWS. He specializes in a variety of security topics, including cryptography and data protection. He focuses on helping AWS customers use AWS security services to strengthen their security posture in the cloud. Public key infrastructure and key management are some of his favorite security topics.

Feng Chen

Feng Chen

Feng is an AWS Cloud Support Engineer based in Melbourne, Australia. He specializes in AWS security services, with deep expertise in ACM, IAM, and AWS Identity Center. He is passionate about helping customers protect their cloud infrastructure. He is also an AWS Golden Jacket owner with all AWS certifications.

Nikhil Kalra

Nikhil Kalra

Nikhil is an AWS Cloud Support Engineer based in Hyderabad, India. He is a subject matter expert in AWS Certificate Manager with expertise in core security services such as Amazon Cognito and IAM. Holding the prestigious AWS Certified Security Specialty certification, he is committed to helping customers implement robust security solutions and protect their cloud infrastructure.

Breaking down data silos: Volkswagen’s approach with Amazon DataZone

Post Syndicated from Bandana Das original https://aws.amazon.com/blogs/big-data/breaking-down-data-silos-volkswagens-approach-with-amazon-datazone/

Over the years, organizations have invested in building purpose-built cloud-based data warehouses that are siloed from one another. One of the major challenges these organizations encounter today is enabling cross-organization discovery and access to data across these siloed data warehouses built using different technology stacks. The data mesh pattern addresses these issues, founded in four principles: domain-oriented decentralized data ownership and architecture, treating data as a product, providing self-serve data infrastructure as a platform, and implementing federated governance. The data mesh pattern helps organizations mimic their organizational structure into data domains and makes it possible to share the data across the organization and beyond to improve their business models.

In 2019, Volkswagen AG and Amazon Web Services (AWS) started their collaboration to co-develop the Digital Production Platform (DPP), with the goal of enhancing production and logistics efficiency by 30% while reducing production costs by the same margin. The DPP was developed to streamline access to data from shop floor devices and manufacturing systems by handling integrations and providing a range of standardized interfaces. However, as applications and use cases evolved on the platform, a significant challenge emerged: the ability to share data across applications stored in isolated data warehouses (within Amazon Redshift in isolated AWS accounts designated for specific use cases), without the need to consolidate data into a central data warehouse. Another challenge was discovering all the available data stored across multiple data warehouses and facilitating a workflow to request access to data across business domains within each plant. The common method used was largely manual, relying on emails and general communication (through tickets and emails). The manual approach not only increased the overhead but also varied from one use case to another in terms of data governance.

In this post, we introduce Amazon DataZone and explore how Volkswagen used Amazon DataZone to build their data mesh, tackle the challenges encountered, and break the data silos. A key aspect of the solution was enabling data providers to automatically publish their data products to Amazon DataZone, serving as a central data mesh for enhanced data discoverability. Additionally, we provide code to guide you through the deployment and implementation process.

Introduction to Amazon DataZone

Amazon DataZone is a data management service that makes it faster and straightforward to catalog, discover, share, and govern data stored across AWS, on-premises, and third-party sources. Key features of Amazon DataZone include the business data catalog, with which users can search for published data, request access, and start working on data in days instead of weeks. In addition, the service facilitates collaboration across teams and helps them manage and monitor data assets across different organizational units. The service also includes the Amazon DataZone portal, which offers a personalized analytics experience for data assets through a web-based application or API. Lastly, Amazon DataZone offers governed data sharing, which makes sure the right data is accessed by the right user for the right purpose with a governed workflow.

Solution overview

The following architecture diagram represents a high-level design that is built on top of the data mesh pattern. It separates source systems, data domain producers (data publishers), data domain subscribers (data consumers), and central governance to highlight the key aspects. This data mesh architecture is specially tailored for cross-AWS account usage. The objective of this approach is to create a foundation for building data governance on a scale, supporting the objectives of data producers and consumers with strong and consistent governance.

This architecture allows for the integration of multiple data warehouses into a centralized governance account that stores all the metadata from each environment.

A data domain producer uses Amazon Redshift as their analytical data warehouse to store, process, and manage structured and semi-structured data. The data domain producers load data into their respective Amazon Redshift clusters through extract, transform, and load (ETL) pipelines they manage, own, and operate. The producers maintain control over their data through Amazon Redshift security features, including column-level access controls and dynamic data masking, supporting data governance at the source. A data domain producer uses Amazon Redshift ETL and Amazon Redshift Spectrum to process and transform raw data into consumable data products. The data products could be Amazon Redshift tables, views, or materialized views.

Data domain producers expose datasets to the rest of the organization by registering them to Amazon DataZone service, which acts as a central data catalog. They can choose what data assets to share, for how long, and how consumers can interact with these. They’re also responsible for maintaining the data and making sure it’s accurate and current.

The data assets from the producers are then published using the data source run to Amazon DataZone in the central governance account. This process populates the technical metadata into the business data catalog for each data asset. The business metadata can be added by business users (data analysts) to provide business context, tags, and data classification for the datasets. This approach provides the required features to allow producers to create catalog entries with Amazon Redshift from all their data warehouses built in with Redshift clusters. In addition, the central data governance account is used to share datasets securely between producers and consumers. It’s important to note that sharing is done through metadata linking alone. No data (except logs) exists in the governance account. The data isn’t copied to the central account; just a reference to the data is used, so that the data ownership remains with the producer.

Amazon DataZone provides a streamlined way to search for data. The Amazon DataZone data portal provides a personalized view for users to discover and search data assets. An Amazon DataZone user (consumer) with permissions to access the data portal can search for assets and submit requests for subscription of data assets using a web-based application. An approver can then approve or reject the subscription request.

When a data domain consumer has access to an asset in the catalog, they can consume it (query and analyze) using the Amazon Redshift query editor. Each consumer runs their own workload based on their use case. In this way, the team can choose the tools for the job to perform analytics and machine learning activities in its AWS consumer environment.

Publishing and registering data assets to Amazon DataZone

To publish a data asset from the producer account, each asset must be registered in Amazon DataZone for consumer subscription. For more information, refer to Create and run an Amazon DataZone data source for Amazon Redshift. In the absence of an automated registration process, required tasks must be completed manually for each data asset.

Using the automated registration workflow, the manual steps can be automated for the Amazon Redshift data asset (Redshift table or view) that needs to be published in an Amazon DataZone domain or when there’s a schema change in an already published data asset.

The following architecture diagram represents how data assets from Amazon Redshift data warehouses have been automatically published to the data mesh created with Amazon DataZone.

The process consists of the following steps:

  1. In the producer account (Account B), the data to be shared resides in a Redshift cluster.
  2. The producer account (Account B) uses a mechanism to trigger the dataset registration AWS Lambda function with a specific payload containing the information and name of the database, schema, table, or view that has a change in metadata.
  3. The Lambda function performs the steps to automatically register and publish the dataset in Amazon DataZone:
    1. Get the Amazon Redshift clusterName, dbName, schemas, and tables from the JSON payload, which is used as the event to trigger the Lambda function.
    2. Get the Amazon DataZone data warehouse blueprint ID.
    3. Enable the blueprint in the data producer account.
    4. Identify the Amazon DataZone Domain ID and project ID for the producer via assuming role in Amazon DataZone account (Account A).
    5. Check if an environment already exists in the project. If not, create an environment.
    6. Create a new Redshift data source by providing the correct Redshift database information in the newly created environment.
    7. Initiate a data source run request in the data source to make the Redshift tables or views available in Amazon DataZone.
    8. Publish the tables or views in the Amazon DataZone catalog.

Prerequisites

The following prerequisites are required before starting:

  • Two AWS accounts to implement the solution have been described in this post. However, you can also use Amazon DataZone to publish data within a single account or across multiple accounts.
    • Amazon DataZone account (Account A) – This is the central data governance account, which will have the Amazon DataZone domain and project.
    • Data domain producer account (Account B) – This account acts as the data domain producer. It has been added as an associated account to Account A.

Prerequisites in data domain producer account (Account B)

As part of this post, we want to publish assets and subscribe to assets from a Redshift cluster that already exists. Complete the following prerequisite steps to set up Account B:

  1. Set up the Redshift cluster, including database, schema, tables, and views (optional). The node type must be from the RA3 family. For more information, see Amazon Redshift provisioned clusters.

    Create a superuser in Amazon Redshift for Amazon DataZone. For the Redshift cluster, the database user you provide in AWS Secrets Manager must have superuser permissions. For reference please see the note section in this QuickStart guide with sample Amazon Redshift data

  2. Store the user’s credentials in Secrets Manager. Select the credential type, enter the credential values, and choose the AWS Key Management Service (AWS KMS) key with which to encrypt the secret.
  3. Add the tags to the Secret Manager secret to allow Amazon DataZone to find this secret and limit the access to a particular Amazon DataZone domain and Amazon DataZone project. The Redshift cluster Amazon Resource Name (ARN) must be added as a tag so it can be used by Amazon Redshift as a valid credential. For reference please see the note section in this QuickStart guide with sample Amazon Redshift data
  4. Add an Amazon DataZone provisioning IAM role and Amazon Redshift manage access IAM role in the secret’s resource policy. The AWS Identity and Access Management (IAM) roles are created as part of the AWS Cloud Development Kit (AWS CDK) deployment (discussed later in this post). The following code shows an example of the Secrets Manager secret’s resource policy. Store the secret ARN in an AWS Systems Manager parameter.
    {
      "Version" : "2012-10-17",
      "Statement" : [ {
        "Effect" : "Allow",
        "Principal" : "*",
        "Action" : "secretsmanager:GetSecretValue",
        "Resource" : "*",
        "Condition" : {
          "ArnEquals" : {
            "aws:PrincipalArn" : [ 
              "arn:aws:iam::<<Data_Producer_Acct_Id(Account B)>>:role/DzRedshiftAccess-<<AWS_Region>>-<< Amazon_DataZone _Domain_Name>>",
              "arn:aws:iam::<<Data_Producer_Acct_Id(Account B)>>:role/DataZoneProvisioning-<< Amazon_DataZone_Account_id(Account A)>>"
            ]
          }
        }
      } ]
    }

    If your secret is encrypted with a custom KMS key, append the key policy with the following statement and add a tag to the key: AmazonDatazoneEnvironment = All. You can skip this step if you’re using an AWS managed KMS key.
    {
        "Effect": "Allow",
        "Principal": {
            "Service": "logs.<<AWS_Region>>.amazonaws.com",
            "AWS": "arn:aws:iam::<<Data_Producer_Acct_Id(Account B)>>:root"
        },
        "Action": [
            "kms:Decrypt",
            "kms:Encrypt",
            "kms:GenerateDataKey*",
            "kms:ReEncrypt*"
        ],
        "Resource": "*"
     },
     {
        "Sid": "AllowDatazoneRoles-DEV",
        "Effect": "Allow",
        "Principal": {
            "AWS": "*"
        },
        "Action": [
            "kms:Decrypt",
            "kms:Describe*",
            "kms:Get*",
            "kms:Encrypt",
            "kms:GenerateDataKey",
            "kms:ReEncrypt*",
            "kms:CreateGrant"
        ],
        "Resource": "*",
        "Condition": {
            "StringLike": {
                "aws:PrincipalArn": [
                    "arn:aws:iam::<<Data_Producer_Acct_Id(Account B)>>:role/aws-service-role/redshift.amazonaws.com/AWSServiceRoleForRedshift",
                    "arn:aws:iam::<<Data_Producer_Acct_Id(Account B)>>:role/datazone_*",
                    "arn:aws:iam::<<Data_Producer_Acct_Id(Account B)>>:role/<<Redshift_Cluster_IAM_Role>>",
                    "arn:aws:iam::<<Data_Producer_Acct_Id(Account B)>>:role/service-role/AmazonDataZoneRedshiftAccess-<<AWS_Region>>-*"
                ]
             }
         }
     } 

  5. Place a mechanism to generate the following payload to trigger the dataset registration Lambda function. The payload must contain the relevant Redshift database, schema, and table or view that you want to publish in the Amazon DataZone domain. The following example code assumes you have three databases in your Redshift cluster and within those databases you have different schemas, tables, and views. You should adjust the payload based on your use case.
    {
        "source": "redshift-user-initiated",
        "detail-type": "Amazon Redshift dataset registration in Amazon DataZone",
        "datasets": [
            {
                "clusterName": "<<YOUR_REDSHIFT_CLUSTER_NAME>>",
                "dbName":"<<YOUR_REDSHIFT_DATABASE_NAME_1>>",
                "schemas": [
                    {
                        "schemaName":"<<YOUR_REDSHIFT_SCHEMA_NAME>>",
                        "addAllTables":false,
                        "addAllViews":false,
                        "tables":[
                            "<<YOUR_REDSHIFT_TABLE_NAME>>",
                            "<<YOUR_REDSHIFT_TABLE_NAME>>"
                        ],
                        "views":[
                            "<<YOUR_REDSHIFT_VIEW_NAME>>"
                        ]
                    }
                ]
            },
            {
                "clusterName": "<<YOUR_REDSHIFT_CLUSTER_NAME>>",
                "dbName":"<<YOUR_REDSHIFT_DATABASE_NAME_2>>",
                "schemas": [
                    {
                        "schemaName":"<<YOUR_REDSHIFT_SCHEMA_NAME>>",
                        "addAllTables":true,
                        "addAllViews":true,
                        "tables":[],
                        "views":[]
                    }
                ]
            },
            {
                "clusterName": "<<YOUR_REDSHIFT_CLUSTER_NAME>>",
                "dbName":"<<YOUR_REDSHIFT_DATABASE_NAME_3>>",
                "schemas": [
                    {
                        "schemaName":"<<YOUR_REDSHIFT_SCHEMA_NAME>>",
                        "addAllTables":true,
                        "addAllViews":false,
                        "tables":[],
                        "views":[
                            "<<YOUR_REDSHIFT_VIEW_NAME>>"
                        ]
                    }
                ]
            }
        ]
    }

Prerequisites in Amazon DataZone account (Account A)

Complete the following steps to set up your Amazon DataZone account (Account A):

  1. Sign in to Account A and make sure you have already deployed an Amazon DataZone domain and a project within that domain. Refer to Create Amazon DataZone domains for instructions to create a domain.
  2. If your Amazon DataZone domain is encrypted with a KMS key, add the data domain account (Account B) to the KMS key policy with the following actions:
    "Action": [
        "kms:Encrypt",
        "kms:Decrypt",
        "kms:ReEncrypt*",
        "kms:GenerateDataKey*",
        "kms:DescribeKey"
    ]

  3. Create an IAM role that is assumable by Account B and make sure the role has a following policy attached and is a member (as contributor) of your Amazon DataZone project. For this post, we call the role dz-assumable-env-dataset-registration-role. By adding this role, you can successfully run the registration Lambda function.
    1. In the following policy, provide the AWS Region and account ID corresponding to where your Amazon DataZone domain is created, and the KMS key ARN used to encrypt the domain:
        {
          "Version": "2012-10-17",
          "Statement": [
              {
                  "Action": [
                      "datazone:CreateDataSource",
                      "datazone:CreateEnvironment",
                      "datazone:CreateEnvironmentProfile",
                      "datazone:GetDataSource",
                      "datazone:GetDataSourceRun",
                      "datazone:GetEnvironment",
                      "datazone:GetEnvironmentProfile",
                      "datazone:GetIamPortalLoginUrl",
                      "datazone:ListDataSources",
                      "datazone:ListDomains",
                      "datazone:ListEnvironmentProfiles",
                      "datazone:ListEnvironments",
                      "datazone:ListProjectMemberships",
                      "datazone:ListProjects",
                      "datazone:StartDataSourceRun",
                      "datazone:UpdateDataSource",
                      "datazone:SearchUserProfiles"
                  ],
                  "Resource": "*",
                  "Effect": "Allow"
              },
              {
                  "Action": [
                      "kms:Decrypt",
                      "kms:DescribeKey",
                      "kms:GenerateDataKey"
                  ],
                  "Resource": "arn:aws:kms:<<account_region>>:<<Datazone_Account_id(Account A)>>
      
      
      }:key/${DataZonekmsKey}",
                  "Effect": "Allow"
              }
          ]
      }

    2. Add Account B in the trust relationship of this role with the following trust relationship:
      {
          "Version": "2012-10-17",
          "Statement": [
              {
                  "Effect": "Allow",
                  "Principal": {
                      "AWS": [
                          "arn:aws:iam::<<Data_Producer_Acct_Id(Account B)>>:root",
                          "arn:aws:iam::<<Datazone_Account_id(Account A)>>:root",
                      ]
                  },
                  "Action": "sts:AssumeRole"
              }
          ]
      }

    3. Add the role as a member of the Amazon DataZone project in which you want to register your data sources. For more information, see Add members to a project.

Additional tools

The following tools are needed to deploy the solution using the AWS CDK:

Deploy the solution

After you complete the prerequisites, use the AWS CDK stack provided on the GitHub repo to deploy the solution for automatic registration of data assets into the Amazon DataZone domain. Complete the following steps:

  1. Clone the repository from GitHub to your preferred integrated development environment (IDE) using the following commands:
    git clone https://github.com/aws-samples/sample-how-to-automate-amazon-redshift-cluster-data-asset-publish-to-amazon-datazone

    $ cd sample-how-to-automate-amazon-redshift-cluster-data-asset-publish-to-amazon-datazone

  2. At the base of the repository folder, run the following commands to build and deploy resources to AWS:
    $ npm install

    $ npm run lint

  3. Sign in to Account B (the data domain producer account) using the AWS CLI with your profile name.
  4. Make sure you have configured the Region in your credential’s configuration file.
  5. Bootstrap the AWS CDK environment with the following commands at the base of the repository folder. Provide the profile name of your deployment account (Account B). Bootstrapping is a one-time activity and is not needed if your AWS account is already bootstrapped.
    $ export AWS_PROFILE=<<PROFILE_NAME>>

    $ npm run cdk bootstrap

  6. Replace the placeholder parameters (marked with the suffix _PLACEHOLDER) in the file config/DataZoneConfig.ts:
    1. Amazon DataZone domain and project name of your Amazon DataZone instance. Make sure all names are in lowercase.
    2. The AWS account ID of the Amazon DataZone account (Account A).
    3. The assumable IAM role from the prerequisites.
    4. The AWS Systems Manager parameter name containing the Secrets Manager secret ARN of the Amazon Redshift credentials.

  7. Use the following command in the base folder to deploy the AWS CDK solution. During deployment, enter y if you want to deploy the changes for some stacks when you see the prompt Do you wish to deploy these changes (y/n)?
    npm run cdk deploy --all

  8. After the deployment is complete, sign in to Account B and open the AWS CloudFormation console to verify that the infrastructure was deployed.

Test automatic data registration to Amazon DataZone

Complete the following steps to test the solution:

  1. Sign in to Account B (producer account).
  2. On the Lambda console, open the datazone-redshift-dataset-registration function.
  3. Under TEST EVENTS, choose Create new test event.
  4. For Event name, enter Redshift, and for Event JSON, enter the following JSON structure (change the cluster, schema, database, and table names according to your environment):
    {
      "source": "redshift-user-initiated",
      "detail-type": "Amazon Redshift dataset registration in Amazon DataZone",
      "datasets": [
        {
          "clusterName": "YOUR_REDSHIFT_CLUSTER_NAME",
          "dbName": "DATABASE_NAME",
          "schemas": [
            {
              "schemaName": "SCHEMA_NAME_1",
              "addAllTables": false,
              "addAllViews": false,
              "tables": [
                "TABLE_NAME"
              ],
              "views": []
            },
            {
              "schemaName": "SCHEMA_NAME_2",
              "addAllTables": false,
              "addAllViews": false,
              "tables": [],
              "views": [
                "VIEW_NAME"
              ]
            }
          ]
        }
      ]
    }

  5. Choose Save.
  6. Choose Invoke.
  7. Open the Amazon DataZone console in Account A where you deployed the resources.
  8. Choose Domains in the navigation pane, then open your domain.
  9. On the domain details page, locate the Amazon DataZone data portal URL in the Summary section. Choose the link to the data portal.

    For more details about accessing Amazon DataZone, refer to How can I access Amazon DataZone?

  10. In the data portal, open your project and choose the Data tab.
  11. In the navigation pane, choose Data sources and find the newly created data source for Amazon Redshift.
  12. Verify that the data source has been successfully published.

After the data sources are published, users can discover the published data and submit a subscription request. The data producer can approve or reject requests. Upon approval, users can consume the data by querying the data in the Amazon Redshift query editor. The following screenshot illustrates data discovery in the Amazon DataZone data portal.

Clean up

Complete the following steps to clean up the resources deployed through the AWS CDK:

  1. Sign in to Account B, go to the Amazon DataZone domain portal, and check there is no subscription for your published data asset. If there is a subscription, either ask the subscriber to unsubscribe or revoke the subscription request.
  2. Delete the published data assets that were created in the Amazon DataZone project by the dataset registration Lambda function.
  3. Delete the remaining resources created using the following command in the base folder:
    npm run cdk destroy –all

Conclusion

Amazon DataZone offers a seamless integration with AWS services, providing a powerful solution for organizations like Volkswagen to break down their data silos and implement effective data mesh architectures through a straightforward implementation highlighted in this post. By using Amazon DataZone, Volkswagen addressed its immediate data sharing hurdles and laid the groundwork for a more agile, data-driven future in automotive manufacturing. The automated data publishing from various warehouses, coupled with standardized governance workflows, has significantly reduced the manual overhead that once slowed down Volkswagen’s data engineering teams. Now, instead of navigating a labyrinth of emails, tickets, and communication, Volkswagen’s data engineers and data scientists can quickly discover and access the data they need, all while maintaining their security and compliance standards.

By using Amazon DataZone, organizations can bring their isolated data together in ways that make it simpler for teams to collaborate while maintaining security and compliance at scale. This approach not only addresses current data governance challenges but also creates a highly scalable foundation for future data-driven innovations. For guidance on establishing your organization’s data mesh with Amazon DataZone, contact your AWS team today.


About the Authors

Bandana Das

Bandana Das

Bandana is a Senior Data Architect in AWS and specializes in data and analytics. She builds event-driven data architectures to support customers in data management and data-driven decision-making. She is also passionate about helping customers on their data management journey to the cloud.

Anirban Saha

Anirban Saha

Anirban is a DevOps Architect at AWS, specializing in architecting and implementation of solutions for customer challenges in the automotive domain. He is passionate about well-architected infrastructures, automation, data-driven solutions, and helping make the customer’s cloud journey as seamless as possible. In his spare time, he likes to keep himself engaged with reading, painting, language learning, and traveling.

Stoyan Stoyanov

Stoyan Stoyanov

Stoyan works for AWS as a DevOps Engineer. He has more than 10 years of experience in software engineering, cloud technologies, DevOps, data engineering, and security.

Sindi Cali

Sindi Cali

Sindi is a ProServe Associate Consultant with AWS Professional Services. She supports customers in building data-driven applications in AWS.

Seamlessly Integrate Data on Google BigQuery and ClickHouse Cloud with AWS Glue

Post Syndicated from Ray Wang original https://aws.amazon.com/blogs/big-data/seamlessly-integrate-data-on-google-bigquery-and-clickhouse-cloud-with-aws-glue/

Migrating from Google Cloud’s BigQuery to ClickHouse Cloud on AWS allows businesses to leverage the speed and efficiency of ClickHouse for real-time analytics while benefiting from AWS’s scalable and secure environment. This article provides a comprehensive guide to executing a direct data migration using AWS Glue ETL, highlighting the advantages and best practices for a seamless transition.

AWS Glue ETL enables organizations to discover, prepare, and integrate data at scale without the burden of managing infrastructure. With its built-in connectivity, Glue can seamlessly read data from Google Cloud’s BigQuery and write it to ClickHouse Cloud on AWS, removing the need for custom connectors or complex integration scripts. Beyond connectivity, Glue also provides advanced capabilities such as a visual ETL authoring interface, automated job scheduling, and serverless scaling, allowing teams to design, monitor, and manage their pipelines more efficiently. Together, these features simplify data integration, reduce latency, and deliver significant cost savings, enabling faster and more reliable migrations.

Prerequisites

Before using AWS Glue to integrate data into ClickHouse Cloud, you must first set up the ClickHouse environment on AWS. This includes creating and configuring your ClickHouse Cloud on AWS, making sure network access and security groups are properly defined, and verifying that the cluster endpoint is accessible. Once the ClickHouse environment is ready, you can leverage the AWS Glue built-in connector to seamlessly write data into ClickHouse Cloud from sources such as Google Cloud BigQuery. You can follow the next section to complete the setup.

  1. Set up ClickHouse Cloud on AWS
    1. Follow the ClickHouse official website to set up environment (remember to allow remote access in the config file if using Clickhouse OSS)
      https://clickhouse.com/docs/get-started/quick-start
  2. Subscribe the ClickHouse Glue marketplace connector
    1. Open Glue Connectors and choose Go to AWS Marketplace
    2. On the list of AWS Glue marketplace connectors, enter ClickHouse in the search bar. Then choose ClickHouse Connector for AWS Glue
    3. Choose View purchase options on the right top of the view
    4. Review Terms and Conditions and choose Accept Terms
    5. Choose Continue to Configuration once it’s enabled
    6. On Follow the vendor’s instructions part in the connector instructions as below, choose the connector enabling link at step 3

Configure AWS Glue ETL Job for ClickHouse Integration

AWS Glue enables direct migration by connecting with ClickHouse Cloud on AWS through built-in connectors, allowing for seamless ETL operations. Within the Glue console, users can configure jobs to read data from S3 and write it directly to ClickHouse Cloud. Using AWS Glue Data Catalog, data in S3 can be indexed for efficient processing, while Glue’s PySpark support allows for complex data transformations, including data type conversions, to support compatibility with ClickHouse’s schema.

  1. Open AWS Glue in the AWS Management Console
    1. Navigate to Data Catalog and Connections
    2. Create a new connection
  2. Configure BigQuery Connection in Glue
    1. Prepare a Google Cloud BigQuery Environment
    2. Create and Store Google Cloud Service Account Key (JSON format) in AWS Secret Manager, you can find the details in BigQuery connections.
    3. The JSON Format content example is as following:
      {
        "type": "service_account",
        "project_id": "h*********g0",
        "private_key_id": "cc***************81",
        "private_key": "-----BEGIN PRIVATE KEY-----\nMI***zEc=\n-----END PRIVATE KEY-----\n",
        "client_email": "clickhouse-sa@h*********g0.iam.gserviceaccount.com",
        "client_id": "1*********8",
        "auth_uri": "https://accounts.google.com/o/oauth2/auth",
        "token_uri": "https://oauth2.googleapis.com/token",
        "auth_provider_x509_cert_url": "https://www.googleapis.com/oauth2/v1/certs",
        "client_x509_cert_url": "https://www.googleapis.com/robot/v1/metadata/x509/clickhouse-sa%40h*********g0.iam.gserviceaccount.com",
        "universe_domain": "googleapis.com"
      }

      • type: service_account.
      • project_id: The ID of the GCP project.
      • private_key_id: A unique ID for the private key within the file.
      • private_key: The actual private key.
      • client_email: The email address of the service account.
      • client_id: A unique client ID associated with the service account.
      • auth_uri, token_uri, auth_provider_x509_cert_url
      • client_x509_cert_url: URLs for authentication and token exchange with Google’s identity and access management systems.
      • universe_domain: The domain name of GCP, googleapis.com
    4. Create Google BigQuery Connection in AWS Glue
    5. Grant the IAM role associated with your AWS Glue job permission for S3, Secret Manager, Glue services, and AmazonEC2ContainerRegistryReadOnly for accessing connectors purchased from AWS Marketplace (reference doc)
  3. Create ClickHouse connection in AWS Glue
    1. Enter clickhouse-connection as its connection name
    2. Choose Create connection and activate connector
  4. Create a Glue job
    1. On the Connectors view as below, select clickhouse-connection and choose Create job
    2. Enter bq_to_clickhouse as its job name and configure gc_connector_role as its IAM Role
    3. Configure BigQuery connection and clickhouse-connection to the Connection property
    4. Choose the Script tab and Edit script. Then choose Confirm on the Edit script popup view.
    5. Copy and paste the following code onto the script editor which can be referred from clickhouse official doc
    6. The source code is as following:
      import sys
      from pyspark.sql import SparkSession
      from awsglue.context import GlueContext
      from awsglue.job import Job
      from awsglue.utils import getResolvedOptions
      
      args = getResolvedOptions(sys.argv, ['JOB_NAME'])
      spark = SparkSession.builder.getOrCreate()
      glueContext = GlueContext(spark.sparkContext)
      job = Job(glueContext)
      job.init(args['JOB_NAME'], args)
      
      connection_options = {
          "connectionName": "Bigquery connection",
          "parentProject": "YOUR_GCP_PROJECT_ID",
          "query": "SELECT * FROM `YOUR_GCP_PROJECT_ID.bq_test_dataset.bq_test_table`",
          "viewsEnabled": "true",
          "materializationDataset": "bq_test_dataset"
      }
      jdbc_url = " jdbc:clickhouse://YOUR_CLICKHOUSE_CONNECTION.us-east-1.aws.clickhouse.cloud:8443/clickhouse_database?ssl=true "
      username = "default"
      password = "YOUR_PASSWORD"
      query = "select * from clickhouse_database.clickhouse_test_table"
      # Add this before writing to test connection
      try:
          # Read from BigQuery with Glue Connection
          print("Reading data from BigQuery...")
          GoogleBigQuery_node1742453400261 = glueContext.create_dynamic_frame.from_options(
              connection_type="bigquery",
              connection_options=connection_options,
              transformation_ctx="GoogleBigQuery_node1742453400261"
          )
          # Convert to DataFrame
          bq_df = GoogleBigQuery_node1742453400261.toDF()
          print("Show data from BigQuery:")
          bq_df.show()
          
          # Write BigQuery Data to Clickhouse with JDBC
          bq_df.write \
          .format("jdbc") \
          .option("driver", 'com.clickhouse.jdbc.ClickHouseDriver') \
          .option("url", jdbc_url) \
          .option("user", username) \
          .option("password", password) \
          .option("dbtable", "clickhouse_test_table") \
          .mode("append") \
          .save()
          
          print("Write BigQuery Data to ClickHouse successfully")
          
          # Read from Clickhouse with JDBC
          reaf_df = (spark.read.format("jdbc")
          .option("driver", 'com.clickhouse.jdbc.ClickHouseDriver')
          .option("url", jdbc_url)
          .option("user", username)
          .option("password", password)
          .option("query", query)
          .option("ssl", "true")
          .load())
          
          print("Show Data from ClickHouse:")
          reaf_df.show()
          
      except Exception as e:
          print(f"ClickHouse connection test failed: {str(e)}")
          raise e
      finally:
          job.commit()

    7. Choose Save and Run on the right top of the current view

Testing and Validation

Testing is crucial to verify data accuracy and performance in the new environment. After the migration completes, run data integrity checks to confirm record counts and data quality in ClickHouse Cloud. Schema validation is essential, as each data field must align correctly with ClickHouse’s format. Running performance benchmarks, such as sample queries, will help verify that ClickHouse’s setup delivers the desired speed and efficiency gains.

  1. The Schema and Data in source BigQuery and destination Clickhouse

  2. AWS Glue output logs

Clean Up

After completing the migration, it’s important to clean up unused resources—such as BigQuery for sample data import and database resources in ClickHouse Cloud—to avoid unnecessary costs. Regarding IAM permissions, adhering to the principle of least privilege is advisable. This involves granting users and roles only the permissions necessary for their tasks and removing unnecessary permissions when they are no longer required. This approach enhances security by minimizing potential threat surfaces. Additionally, reviewing AWS Glue job costs and configurations can help identify optimization opportunities for future migrations. Monitoring overall costs and analyzing usage can reveal areas where code or configuration improvements may lead to cost savings.

Conclusion

AWS Glue ETL offers a robust and user-friendly solution for migrating data from BigQuery to ClickHouse Cloud on AWS. By utilizing Glue’s serverless architecture, organizations can perform data migrations that are efficient, secure, and cost-effective. The direct integration with ClickHouse streamlines data transfer, supporting high performance and flexibility. This migration approach is particularly well-suited for companies looking to enhance their real-time analytics capabilities on AWS.


About the Authors

Ray Wang

Ray Wang

Ray is a Senior Solutions Architect at AWS. With 12+ years of experience in the IT industry, Ray is dedicated to building modern solutions on the cloud, especially in NoSQL, big data, machine learning, and Generative AI. As a hungry go-getter, he passed all 12 AWS certificates to make his technical field not only deep but wide. He loves to read and watch sci-fi movies in his spare time.

Robert Chung

Robert Chung

Robert is a Solutions Architect at AWS with expertise across Infrastructure, Data, AI, and Modernization technologies. He has supported numerous financial services customers in driving cloud-native transformation, advancing data analytics, and accelerating mainframe modernization. His experience also extends to modern AI-DLC practices, enabling enterprises to innovate faster. With this background, Robert is well-equipped to address complex enterprise challenges and deliver impactful solutions.

Tomohiro Tanaka

Tomohiro Tanaka

Tomohiro is a Senior Cloud Support Engineer at Amazon Web Services (AWS). He’s passionate about helping customers use Apache Iceberg for their data lakes on AWS. In his free time, he enjoys a coffee break with his colleagues and making coffee at home.

Stanley Chukwuemeke

Stanley Chukwuemeke

Stanley is a Senior Partner Solutions Architect at AWS. He works with AWS technology partners to grow their business by creating joint go-to-market solutions using AWS data, analytics and AI services. He’s worked with data most of his career and passionate about database modernization and cloud adoption strategy to help drive enterprise modernization initiatives across industries.

Optimize efficiency with language analyzers using scalable multilingual search in Amazon OpenSearch Service

Post Syndicated from Sunil Ramachandra original https://aws.amazon.com/blogs/big-data/optimize-efficiency-with-language-analyzers-using-scalable-multilingual-search-in-amazon-opensearch-service/

Organizations manage content across multiple languages as they expand globally. Ecommerce platforms, customer support systems, and knowledge bases require efficient multilingual search capabilities to serve diverse user bases effectively. This unified search approach helps multinational organizations maintain centralized content repositories while making sure users, regardless of their preferred language, can effectively find and access relevant information.

Building multi-language applications using language analyzers with OpenSearch commonly involves a significant challenge: multi-language documents require manual preprocessing. This means that in your application, for every document, you must first identify each field’s language, then categorize and label it, storing content in separate, pre-defined language fields (for example, name_en, name_es, and so on) in order to use language analyzers in search to improve search relevancy. This client-side effort is complex, adding workload for language detection, potentially slowing data ingestion, and risking accuracy issues if languages are misidentified. It’s a labor-intensive approach. However, Amazon OpenSearch Service 2.15+ introduces an AI-based ML inference processor. This new feature automatically identifies and tags document languages during ingestion, streamlining the process and removing the burden from your application.

By harnessing the power of AI and using context-aware data modeling and intelligent analyzer selection, this automated solution streamlines document processing by minimizing manual language tagging, and enables automatic language detection during ingestion, providing organizations sophisticated multilingual search capabilities.

Using language identification in OpenSearch Service offers the following benefits:

  • Enhanced user experience – Users can now find relevant content regardless of the language they search in
  • Increased content discovery – The service can surface valuable content across language silos
  • Improved search accuracy – Language-specific analyzers provide better search relevance
  • Automated processing – You can reduce manual language tagging and classification

In this post, we share how to implement a scalable multilingual search solution using OpenSearch Service.

Solution overview

The solution eliminates manual language preprocessing by automatically detecting and handling multilingual content during document ingestion. Instead of manually creating separate language fields (en_notes, es_notes, and so on) or implementing custom language detection systems, the ML inference processor identifies languages and creates appropriate field mappings.

This automated approach improves accuracy compared to traditional manual methods and reduces development complexity and processing overhead, allowing organizations to focus on delivering better search experiences to their global users.

The solution comprises the following key components:

  • ML inference processor – Invokes ML models during document ingestion to enrich content with language metadata
  • Amazon SageMaker integration – Hosts pre-trained language identification models that analyze text fields and return language predictions
  • Language-specific indexing – Applies appropriate analyzers based on detected languages, providing proper handling of stemming, stop words, and character normalization
  • Connector framework – Enables secure communication between OpenSearch Service and Amazon SageMaker endpoints through AWS Identity and Access Management (IAM) role-based authentication.

The following diagram illustrates the workflow of the language detection pipeline.

Workflow of the language detection pipeline

 Figure 1: Workflow of the language detection pipeline

This example demonstrates text classification using XLM-RoBERTa-base for language detection on Amazon SageMaker. You have flexibility in choosing your models and can alternatively use the built-in language detection capabilities of Amazon Comprehend.

In the following sections, we walk through the steps to deploy the solution. For detailed implementation instructions, including code examples and configuration templates, refer to the comprehensive tutorial in the OpenSearch ML Commons GitHub repository.

Prerequisites

You must have the following prerequisites:

Deploy the model

Deploy a pre-trained language identification model on Amazon SageMaker. The XLM-RoBERTa model provides robust multilingual language detection capabilities suitable for most use cases.

Configure the connector

Create an ML connector to establish a secure connection between OpenSearch Service and Amazon SageMaker endpoints, primarily for language detection tasks. The process begins with setting up authentication through IAM roles and policies, applying proper permissions for both services to communicate securely.

After you configure the connector with the appropriate endpoint URLs and credentials, the model is registered and deployed in OpenSearch Service and its modelID is used in subsequent steps.

POST /_plugins/_ml/models/_register
{
  "name": "sagemaker-language-identification",
  "version": "1",
  "function_name": "remote",
  "description": "Remote model for language identification",
  "connector_id": "your_connector_id"
}

Sample response:

{
  "task_id": "hbYheJEBXV92Z6oda7Xb",
  "status": "CREATED",
  "model_id": "hrYheJEBXV92Z6oda7X7"
}

After you configure the connector, you can test is by sending text to the model through OpenSearch Service, and it will return the detected language (for example, sending “Say this is a test” returns en for English).

POST /_plugins/_ml/models/your_model_id/_predict
{
  "parameters": {
    "inputs": "Say this is a test"
  }
}
{
  "inference_results": [
    {
      "output": [
        {
          "name": "response",
          "dataAsMap": {
            "response": [
              {
                "label": "en",
                "score": 0.9411176443099976
              }
            ]
          }
        }
      ]
    }
  ]
}

Set up the ingest pipeline

Configure the ingest pipeline, which uses ML inference processors to automatically detect the language of the content in the name and notes fields of incoming documents. After language detection, the pipeline creates new language-specific fields by copying the original content to new fields with language suffixes (for example, name_en for English content).

The pipeline uses an ml_inference processor to perform the language detection and copy processors to create the new language-specific fields, making it straightforward to handle multilingual content in your OpenSearch Service index.

PUT _ingest/pipeline/language_classification_pipeline{
  "description": "ingest task details and classify languages",
  "processors": [
    {
      "ml_inference": {
        "": "6s71PJQBPmWsJ5TTUQmc",
        "input_map": [
          {
            "inputs": "name"
          },
          {
            "inputs": "notes"
          }
        ],
        "output_map": [
          {
            "predicted_name_language": "response[0].label"
          },
          {
            "predicted_notes_language": "response[0].label"
          }
        ]
      }
    },
    {
      "copy": {
        "source_field": "name",
        "target_field": "name_{{predicted_name_language}}",
        "ignore_missing": true,
        "override_target": false,
        "remove_source": false
      }
    }
  ]
}
{
  "acknowledged": true
}

Configure the index and ingest documents

Create an index with the ingest pipeline that automatically detects the language of incoming documents and applies appropriate language-specific analysis. When documents are ingested, the system identifies the language of key fields, creates language-specific versions of those fields, and indexes them using the correct language analyzer. This allows for efficient and accurate searching across documents in multiple languages without requiring manual language specification for each document.

Here’s a sample index creation API call demonstrating different language mappings.

PUT /task_index
{
  "settings": {
    "index": {
      "default_pipeline": "language_classification_pipeline"
    }
  },
  "mappings": {
    "properties": {
      "name_en": { "type": "text", "analyzer": "english" },
      "name_es": { "type": "text", "analyzer": "spanish" },
      "name_de": { "type": "text", "analyzer": "german" },
      "notes_en": { "type": "text", "analyzer": "english" },
      "notes_es": { "type": "text", "analyzer": "spanish" },
      "notes_de": { "type": "text", "analyzer": "german" }
    }
  }
}

Next, ingest this input document in German

{
  "name": "Kaufen Sie Katzenminze",
  "notes": "Mittens mag die Sachen von Humboldt wirklich."
}

The German text used in the preceding code will be processed using a German-specific analyzer, supporting proper handling of language-specific characteristics such as compound words and special characters.

After successful ingestion into OpenSearch Service, the resulting document appears as follows:

{
  "_source": {
    "predicted_notes_language": "en",
    "name_en": "Buy catnip",
    "notes": "Mittens really likes the stuff from Humboldt.",
    "predicted_name_language": "en",
    "name": "Buy catnip",
    "notes_en": "Mittens really likes the stuff from Humboldt."
  }
}

Search documents

This step demonstrates the search capability after the multilingual setup. By using a multi_match query with name_* fields, it searches across all language-specific name fields (name_en, name_es, name_de) and successfully finds the Spanish document when searching for “comprar” because the content was properly analyzed using the Spanish analyzer. This example shows how the language-specific indexing enables accurate search results in the correct language without needing to specify which language you’re searching in.

GET /task_index/_search
{
  "query": {
    "multi_match": {
      "query": "comprar",
      "fields": ["name_*"]
    }
  }
}

This search correctly finds the Spanish document because the name_es field is analyzed using the Spanish analyzer:

{
  "hits": {
    "total": { "value": 1, "relation": "eq" },
    "max_score": 0.9331132,
    "hits": [
      {
        "_index": "task_index",
        "_id": "3",
        "_score": 0.9331132,
        "_source": {
          "name_es": "comprar hierba gatera",
          "notes": "A Mittens le gustan mucho las cosas de Humboldt.",
          "predicted_notes_language": "es",
          "predicted_name_language": "es",
          "name": "comprar hierba gatera",
          "notes_es": "A Mittens le gustan mucho las cosas de Humboldt."
        }
      }
    ]
  }
}

Cleanup

To avoid ongoing charges and delete the resources created in this tutorial, perform the following cleanup steps

  1. Delete the Opensearch service domain. This stops both storage costs for your vectorized data and any associated compute charges.
  2. Delete the ML connector that links your OpenSearch service to your machine learning model.
  3. Finally, delete your Amazon SageMaker endpoints and resources.

Conclusion

Implementing multilingual search with OpenSearch Service can help organizations break down language barriers and unlock the full value of their global content. The ML inference processor provides a scalable, automated approach to language detection that improves search accuracy and user experience.

This solution addresses the growing need for multilingual content management as organizations expand globally. By automatically detecting document languages and applying appropriate linguistic processing, businesses can deliver comprehensive search experiences that serve diverse user bases effectively.


About the authors

Sunil Ramachandra

Sunil Ramachandra

Sunil is a Senior Solutions Architect at AWS, enabling hyper-growth Independent Software Vendors (ISVs) to innovate and accelerate on AWS. He partners with customers to build highly scalable and resilient cloud architectures. When not collaborating with customers, Sunil enjoys spending time with family, running, meditating, and watching movies on Prime Video.

Mingshi Liu

Mingshi Liu

Mingshi is a Machine Learning Engineer at AWS, primarily contributing to OpenSearch, ML Commons and Search Processors repo. Her work focuses on developing and integrating machine learning features for search technologies and other open-source projects.

Sampath Kathirvel

Sampath Kathirvel

Sampath is a Senior Solutions Architect at AWS who guides leading ISV organizations in their cloud transformation journey. His expertise lies in crafting robust architectural frameworks and delivering strategic technical guidance to help businesses thrive in the digital landscape. With a passion for technology innovation, Sampath empowers customers to leverage AWS services effectively for their mission-critical workloads.

Deploying AI models for inference with AWS Lambda using zip packaging

Post Syndicated from Ayush Kulkarni original https://aws.amazon.com/blogs/compute/deploying-ai-models-for-inference-with-aws-lambda-using-zip-packaging/

AWS Lambda provides an event-driven programming model, scale-to-zero capability, and integrations with over 200 AWS services. This can make it a good fit for CPU-based inference applications that use customized, lightweight models and complete within 15 minutes.

Users usually package their function code as container images when using machine learning (ML) models that are larger than 250 MB, which is the Lambda deployment package size limit for zip files. In this post, we demonstrate an approach that downloads ML models directly from Amazon S3 into your function’s memory so that you can continue packaging your function code using zip files. To optimize startup latency without implementing application-level performance optimizations, we use Lambda SnapStart. SnapStart is an opt-in capability available for Java, Python, and .NET functions that optimizes startup latency—from 16.5s down to 1.6s for the application used in this post.

Application architecture

In this post, we demonstrate how to build a chatbot, using a 4-bit quantized version of the DeepSeek-R1-Distill-Qwen-1.5B-GGUF model for inference along with Lambda Function URL (FURL) and Lambda Web Adapter (LWA) to stream text responses. A FURL is a dedicated HTTP(s) endpoint for your Lambda function, and you can use LWA, an open-source project available on AWS Labs, for familiar web application frameworks (such as FastAPI, Next.JS, or Spring Boot) with Lambda. For a detailed explanation of how this response streaming architecture works, refer to this AWS Compute post.

Today, Lambda functions are run on CPU-based Amazon Elastic Compute Cloud (Amazon EC2) instances that use x86 and ARM64 architectures. For this reason, you must use SDKs that enable large language model (LLM) inference on CPUs. In this post, we also demonstrate how to use the llama.cpp project (through the llama-cpp-python library) and the FastAPI web framework to handle web requests. To use models that exceed the 250 MB zip package size limit of Lambda, you can download them from an S3 bucket during function initialization. The following figure describes this architecture in detail.

Architecture diagram demonstrating an AI inference workload with AWS Lambda FURLs and AWS Lambda Web Adapter

Figure 1: Application architecture

You can refer to this GitHub repository for the application code used in this example.

Downloading ML models during function initialization

As an alternative to packaging ML models using OCI container images, you can download them from durable storage, such as Amazon S3, during initialization. Initialization (or INIT) refers to the phase when Lambda downloads your function code, starts the language runtime and runs your function initialization code, which is code outside the handler. Loading large files directly into memory can be faster than first downloading them to disk and then loading them into memory. To do so, you can use a Linux capability called memfd, to directly download the ML model from Amazon S3 directly into memory, while referencing it using a standard file descriptor. Referencing the model using a file descriptor is necessary for llama.cpp to successfully import the model. This is comprised of two steps.

First, create a memory-only file descriptor:


    libc = ctypes.CDLL("libc.so.6", use_errno=True)
    MFD_CLOEXEC = 1
    
    memfd_create = libc.memfd_create
    memfd_create.argtypes = [ctypes.c_char_p, ctypes.c_uint]
    memfd_create.restype = ctypes.c_int
    
    fd = memfd_create(b"model", MFD_CLOEXEC)
    if fd == -1:
        errno = ctypes.get_errno()
    raise OSError(errno, f"memfd_create failed: {os.strerror(errno)}")
    
    return fd

Then, download the model into the memory-mapped file referenced by the previously created file descriptor.

def download_model_to_memfd(bucket, key, chunk_size=100*1024*1024):  # 100MB chunks

    s3 = boto3.client('s3')
    
    # Get file size
    response = s3.head_object(Bucket=bucket, Key=key)
    file_size = response['ContentLength']
    
    # Create memory file
    fd = create_memfd()
    
    # Pre-allocate the full file size
    try:
        os.ftruncate(fd, file_size)
    except OSError as e:
        logger.error(f"Failed to allocate {file_size/1024/1024:.2f}MB in memory: {e}")
        cleanup_fd(fd)
        raise RuntimeError(f"Not enough memory to load model of size {file_size/1024/1024:.2f}MB")
    
    # Calculate parts
    parts = []
    for start in range(0, file_size, chunk_size):
        end = min(start + chunk_size - 1, file_size - 1)
        parts.append({'start': start, 'end': end})
    
    logger.info(f"Downloading {file_size/1024/1024:.2f}MB in {len(parts)} parts")
    
    # Download parts concurrently
    download_func = partial(download_part, s3, bucket, key, fd)
    with ThreadPoolExecutor(max_workers=multiprocessing.cpu_count()) as executor:
        executor.map(download_func, parts)
    
    fd_path = f"/proc/self/fd/{fd}"
    return fd, fd_path

Querying the chatbot

After deploying our sample chatbot application, we begin interacting with it.

The first query to the chatbot results in a new execution environment being initialized. When Lambda runs the initialization code described in the previous section, your ML model is directly downloaded from Amazon S3 into the function’s memory. After this, Lambda runs the function’s handler method. Looking at the X-Ray trace segment in the following figure, we observe that the first Init times out after 10 s. The second Init completes in 16.68 s. Furthermore, the first Init times out because Lambda limits the duration of this phase to 10s. If Init takes longer than this, then Lambda retries it during function invocation applying the function’s configured execution duration timeout.

Screenshot of AWS X-Ray Segments demonstrating INIT duration of 16.68 s

Figure 2: Init duration, indicated by AWS X-Ray trace segment

Optimizing startup performance with SnapStart

To optimize function startup latency, you can use Lambda SnapStart. SnapStart is designed to optimize startup latency stemming from long-running function initialization code. Lambda uses SnapStart to initialize your function when you publish a function version, as shown in the following figure. Then, Lambda takes a Firecracker microVM snapshot of the memory and disk state of the initialized execution environment, encrypts the snapshot, and intelligently caches it to optimize retrieval latency.

Screenshot of AWS Lambda Console showing how to enable SnapStart for your Lambda function

Figure 3: Enabling SnapStart

Querying the chatbot again shows a significant speed-up in initialization latency. You can verify this by viewing your function’s Amazon CloudWatch Logs, and searching for the “RESTORE_REPORT” log line, as shown in the following figure. For the sample application used, restore duration is 1.39 s. This is a considerable improvement over the Init duration of 16.68 s. Performance results may vary. But best of all, you don’t need to change a single line of code to achieve this improvement!

Screenshot of Amazon CloudWatch Logs demonstrating RESTORE duration of 1.39 s

Figure 4: Achieving faster startup latency with SnapStart

Tuning inference performance

Inference performance depends on the CPU resources allocated to your function. Lambda allocates CPU power in proportion to the amount of memory configured for your function. Allocating more memory results in faster inference results, measured by the rate at which prompt tokens are evaluated (tokens evaluated per second), and the rate at which output tokens are produced (tokens generated per second). For this example, we allocate the maximum—in other words 10 GB memory—to maximize performance. Performance results obtained at other memory size configurations are included in the following table. As the table shows, doubling the memory allocated from 5 GB to 10 GB results in an 83% improvement in tokens evaluated and generated (per second), with only a 24% increase in billed GB-seconds. Performance results may vary. Refer to the sample code to instrument performance at different memory sizes.

Memory
Size (MB)
Tokens evaluated per second

Tokens generated

per second

Billed Duration (ms)

Billed

GB-seconds

10240 44.68 29.53 36,660 366.60
9216 41.67 26.77 37,690 339.21
8192 37.17 22.05 44,298 354.38
7168 33.67 21.78 44,818 313.73
6144 28.89 18.43 52,579 315.47
5120 24.41 16.07 59,036 295.18
4096 19.07 12.94 72,648 290.59
3072 13.39 9.20 101,468 304.40
2048 10.01 6.77 135,862 271.72

Table 1: Inference performance at different memory sizes

Understanding how application costs scale with usage

To estimate the cost of running this workload, we begin by making some assumptions about our traffic patterns. We estimate about 30,000 inference calls per month to our Lambda function, with each inference call averaging 10s in duration. We set function memory to 10 GB, because it represents the ideal price-performance for our use case. We deploy our application in the US-West-2 (Oregon) AWS Region. Initially, because our number of invokes is low, we assume a 5% cold-start rate. In other words, 5% of invokes result in a cold-start when a new execution environment is created. When using SnapStart with the Lambda managed Python runtime, you are charged for caching your function’s snapshot and for restoring execution from your function’s snapshot.

With these parameters, the monthly Lambda bill is $91.1, calculated as shown in the following table. The monthly costs shown in the table are only illustrative.

Charge Calculation Monthly Cost
Compute 30,000 inferences * 10 seconds per inference * 10 GB (configured memory) * $0.00001667 per GB-second $50.01
Requests $0.2 per million requests * 30,000 inferences $0.006
SnapStart – Cache 10 GB function memory * 2.59M GB-seconds per month * $0.0000015046 per GB-second $38.99
SnapStart – Restore 10 GB function memory * $0.0001397998 per GB restore * 1500 cold-starts $2.09
Total Compute + Requests + SnapStart Cache + SnapStart Restore $91.1

At low invocation volume, the added charges for the SnapStart account for approximately 50% of total monthly cost. For this added charge, cold-start latency reduces from 16.68 s to1.39 s, without having to implement complex optimizations ourselves. We can demonstrate how these costs scale with usage. We assume that our chatbot grows in popularity with traffic increasing 10 times to 300,000 monthly inference calls. Although cold-start rates for individual Lambda functions can vary due to several factors, Lambda’s re-use of execution environments generally results in cold-start rates decreasing with higher traffic volume. For the purposes of this example, we assume that our cold-start rate drops to 1% of all invokes with the 10 times growth in traffic.With these assumptions, our monthly Lambda bill at 10 times higher traffic volume is $543.3. Added charges for SnapStart now constitute less than 10% of our total bill, as shown in the following table. Monthly costs shown in this table are only illustrative.

Charge Calculation Monthly Cost
Compute 300,000 inferences * 10 seconds per inference * 10 GB (configured memory) * $0.00001667 per GB-second $500.01
Requests $0.2 per million requests * 300,000 inferences $0.06
SnapStart – Cache 10 GB function memory * 2.59M GB-seconds per month * $0.0000015046 per GB-second $38.99
SnapStart – Restore 10 GB function memory * $0.0001397998 per GB restore * 3000 cold-starts $4.18
Total Compute + Requests + SnapStart Cache + SnapStart Restore $543.24

Considerations


Lambda functions are run on CPU-based EC2 instances. If your ML models need GPU-based inference, foundational LLMs, or exceed the Lambda limits on execution duration (15 minutes) and function memory (10 GB), then you can use AWS Machine Learning, AWS Generative AI, or AWS Compute services.

Moreover, you should know the following things about Lambda SnapStart:

Handling uniqueness: If your initialization code generates unique content that is included in the snapshot, then the content isn’t unique when it’s reused across execution environments. To maintain uniqueness when using SnapStart, you must generate unique content after initialization, such as if your code uses custom random number generation that doesn’t rely on built-in-libraries or caches any information such as DNS entries that might expire during initialization. To learn how to restore uniqueness, visit Handling uniqueness with Lambda SnapStart in the Lambda Developer Guide.

Performance tuning: To maximize performance, we recommend that you preload dependencies and initialize resources that contribute to startup latency in your initialization code instead of in the function handler. This moves the latency associated with these operations during version publish, rather than during function invocation and can yield faster startup performance. To learn more, visit Performance tuning for Lambda SnapStart in the Lambda Developer Guide.

Networking best practices: The state of connections that your function establishes during the initialization phase isn’t guaranteed when Lambda resumes your function from a snapshot. In most cases, network connections that an AWS SDK establishes automatically resume. For other connections, review the Networking best practices for Lambda SnapStart in the Lambda Developer Guide.

Conclusion

In this post, we demonstrated how you can download ML models directly from Amazon S3 into your function’s memory, enabling you to deploy your AWS Lambda functions using zip packages. To optimize startup latency without implementing application-level performance optimizations, we also demonstrated the use of Lambda SnapStart, an opt-in capability available for Java, Python, and .NET. For the application used in this post, SnapStart reduced startup latency from 16.68 s down to 1.39 s.

To learn more about Lambda, refer to our documentation. For details about Lambda SnapStart, refer to our launch posts for Java, Python and .Net, and the documentation.

You can refer to this GitHub repository for the application code used in this example.

How Laravel Nightwatch handles billions of observability events in real time with Amazon MSK and ClickHouse Cloud

Post Syndicated from Masudur Rahaman Sayem original https://aws.amazon.com/blogs/big-data/how-laravel-nightwatch-handles-billions-of-observability-events-in-real-time-with-amazon-msk-and-clickhouse-cloud/

Laravel, one of the world’s most popular web frameworks, launched its first-party observability platform, Laravel Nightwatch, to provide developers with real-time insights into application performance. Built entirely on AWS managed services and ClickHouse Cloud, the service already processes over one billion events per day while maintaining sub-second query latency, giving developers instant visibility into the health of their applications.

By combining Amazon Managed Streaming for Apache Kafka (Amazon MSK) with ClickHouse Cloud and AWS Lambda, Laravel Nightwatch delivers high-volume, low-latency monitoring at scale, while maintaining the simplicity and developer experience Laravel is known for.

The challenge: Delivering real-time monitoring for a global developer community

The Laravel framework powers millions of applications worldwide, serving billions of requests each month. Each request can generate potentially hundreds of observability events, such as database queries, queued jobs, cache lookups, emails, notifications, and exceptions. For Nightwatch’s launch, Laravel anticipated instant adoption from its global community, with tens of thousands of applications sending events around the clock from day one.

Laravel Nightwatch needed an architecture that could:

  • Ingest millions of JSON events per second from customer applications reliably.
  • Provide sub-second analytical queries for real-time dashboards.
  • Scale horizontally to handle unpredictable traffic spikes.
  • Deliver all of this in a cost-effective, low-maintenance manner.

The challenge was to process data on a global scale and provide deep insights into application health without compromising on a straightforward setup experience for developers.

The solution: A decoupled streaming and analytics pipeline

Laravel Nightwatch implemented a dual-database, streaming-first architecture, shown in the preceding figure, that separates transactional and analytical workloads.

  • Transactional workloads – user accounts, organization settings, billing, and similar workloads run on Amazon RDS for PostgreSQL.
  • Analytical workloads – telemetry events, metrics, query logs, and request traces are handled by ClickHouse Cloud.

Key components

The key components of the solution include the following:

  1. Ingestion layer
    • Amazon API Gateway receives telemetry from Laravel agents embedded in customer applications
    • Lambda validates and enriches events. Validated and enriched events are published to Amazon MSK, partitioned for scalability
  2. Streaming to analytics
    • ClickPipes in ClickHouse Cloud subscribe directly to MSK topics, reducing the need to build and manage extract, transform, and load (ETL) pipelines
    • Materialized views in ClickHouse pre-aggregate and transform raw JSON into query-ready formats
  3. Dashboards and delivery

Why Amazon MSK and ClickHouse Cloud?

Nightwatch requires a durable, horizontally scalable, and low maintenance streaming backbone.

With Amazon MSK Express brokers, we have achieved over 1 million events per second during load testing, benefiting from low-latency, elastic scaling, and simplified operations. MSK Express brokers require no storage sizing or provisioning, scale up to 20 times faster, and recover 90% quicker than standard Apache Kafka brokers—all while enforcing best-practice defaults and client quotas for reliable performance. Its seamless integration with other AWS services—such as Lambda, Amazon Simple Storage Service (Amazon S3), and Amazon CloudWatch—made it straightforward to build a resilient, end-to-end streaming architecture.

To ingest and transform these events in real time, Nightwatch uses ClickHouse Cloud and its managed integration platform, ClickPipes. ClickHouse Cloud excels at analytical workloads by delivering up to 100 times faster query performance for analytics compared to traditional row-based databases. Its advanced compression algorithms provide up to 90% storage savings, significantly reducing infrastructure costs while maintaining high performance. With its columnar architecture and optimized execution engine, ClickHouse Cloud can query billions of rows in under 1 second, enabling Laravel Nightwatch to serve real-time dashboards and analytics at global scale.

By integrating Amazon MSK and ClickHouse using ClickPipes, Laravel also reduced the operational burden of building and managing ETL pipelines, reducing latency and complexity.

Overcoming challenges

Testing complexity

While synthetic benchmarking and test datasets yield useful results, a more realistic workload is required to rigorously test infrastructure and code before deployment to production. The team used Terraform to manage infrastructure alongside application code, creating multiple dev and test environments, and allowing them to test the platform internally with their own applications before each release.

Multi-region infrastructure

The need to cater to multiple data storage regions also brought challenges—with latency, complexity, and cost the foremost concerns. However, the AWS, ClickHouse Cloud, and Cloudflare stack made available a powerful set of networking tools and scaling options. While VPC peering, RDS replication, and global server load balancing did the heavy lifting on the networking side, the ability to scale and right-size each resource kept costs to a minimum.

Query performance at scale

Materialized views, intelligent time-series partitioning, and specialized ClickHouse codecs helped ensure that queries remained sub-second even as data volumes grew into the billions. Meanwhile, compute separation allowed distinct workloads to scale separately while accessing the same data, with clusters right-sized horizontally and vertically depending on the requirements of each load.

Results

Laravel Nightwatch’s launch exceeded expectations:

  • 5,300 users registered in the first 24 hours
  • 500 million events processed on day one
  • 97 ms average dashboard request latency
  • 760,000 exceptions logged and analyzed in real time

By building on Amazon MSK and ClickHouse Cloud, we were able to scale from zero to billions of events without sacrificing performance or developer experience.

What’s next

Laravel plans to expand Nightwatch with:

  • More regions to cater to customers with data sovereignty requirements outside the US and EU
  • Broader data collection to provide even deeper insight into customers’ applications
  • SOC 2 certification to cater to customers with tighter compliance requirements
  • More advanced monitoring and analysis to identify issues before they affect users

The current architecture comfortably supports applications of all sizes, from hobby to enterprise (including a generous free tier), and is designed to handle over one trillion monthly events without performance degradation.

Conclusion

Laravel Nightwatch demonstrates how Amazon MSK, ClickHouse Cloud, and AWS serverless technologies can be combined to build a cost-effective, real-time monitoring platform at global scale. By designing for scale from day one, Laravel delivered sub-second analytics across billions of events, while maintaining the developer-friendly experience their community expects.


About the authors

Jess Archer

Jess Archer

Jess is an Engineering Manager and Head of Nightwatch at Laravel, focusing on application observability, performance monitoring, and developer experience. She leads the Nightwatch team while staying hands-on in the codebase. Prior to Laravel, Jess worked on clinical data collection platforms, software for law enforcement, and anti-phishing solutions in banking. She later contributed extensively to Laravel’s open-source ecosystem before moving into her current leadership role. Jess is deeply passionate about open source and creating tools that make developers more productive.

James Carpenter

James Carpenter

James is a Senior Infrastructure Engineer joined Laravel in 2024 as Infrastructure Lead for the Nightwatch team, bringing experience from 15 years in sport and healthcare. Specialising in DevOps and Infrastructure, he is passionate about solving complex problems and creating exceptional experiences for both customers and developers.

Johnny Mirza

Johnny Mirza

Johnny is a Solution Architect with ClickHouse, working with users across APAC. With over 20 years of background in solutions engineering, he’s experienced in architecting and enabling solutions for enterprise clients in the telecommunications, media, insurance, and financial services sectors. Johnny has a high level of expertise of integration between both public cloud and on-premise infrastructure, while focussing on service assurance, monitoring platforms, and open-source technologies. Prior to ClickHouse, Johnny was part of the solution engineering teams at Confluent, Splunk, and Optus, to name a few.

Masudur Rahaman Sayem

Masudur Rahaman Sayem

Masudur is a Streaming Data Architect at AWS with over 25 years of experience in the IT industry. He collaborates with AWS customers worldwide to architect and implement sophisticated data streaming solutions that address complex business challenges. As an expert in distributed computing, Sayem specializes in designing large-scale distributed systems architecture for maximum performance and scalability. He has a keen interest and passion for distributed architecture, which he applies to designing enterprise-grade solutions at internet scale.

How to export to Amazon S3 Tables by using AWS Step Functions Distributed Map

Post Syndicated from Chetan Makvana original https://aws.amazon.com/blogs/compute/how-to-export-to-amazon-s3-tables-by-using-aws-step-functions-distributed-map/

Companies running serverless workloads often need to perform extract, transform, and load (ETL) operations on data files stored in Amazon Simple Storage Service (Amazon S3) buckets. Though traditional approaches such as an AWS Lambda trigger for Amazon S3 or Amazon S3 Event Notifications can handle these operations, they might fall short when workflows require enhanced visibility, control, or human intervention. For example, some processes might need manual review of failed records or explicit approval before proceeding to subsequent stages. Customer orchestration solutions to these issues can prove to be complex and error prone.

AWS Step Functions address these challenges by providing built-in workflow management and monitoring capabilities. The Step Functions Distributed Map feature is designed for high-throughput, parallel data processing workflows so that companies can handle complex ETL jobs, fan-out processing, and data visualization at scale. Distributed Map handles each dataset item as an independent child workflow, processing millions of records while maintaining built-in concurrency controls, fault tolerance, and progress tracking. The processed data can be seamlessly exported to various destinations, including Amazon S3 Tables with Apache Iceberg support.

In this post, we show how to use Step Functions Distributed Map to process Amazon S3 objects and export results to Amazon S3 Tables, creating a scalable and maintainable data processing pipeline.

See the associated GitHub repository for detailed instructions about deploying this solution as well as sample code.

Solution overview

Consider a consumer electronics company that regularly participates in industry trade shows and conferences. During these events, interested attendees fill out paper sign-up forms to request product demos, receive newsletters, or join early access programs. After the events, the company’s team scans hundreds of thousands of these forms and uploads them to Amazon S3.Rather than manually reviewing each form, the company wants to automate the extraction of key customer details such as name, email address, mailing address, and interest areas. They’d like to store this structured data in S3 Tables with Apache Iceberg format for downstream analytics and marketing campaign targeting.

Let’s look at how this post’s solution uses Distributed Map to process PDFs in parallel, extract data using Amazon Textract, and write the cleaned output directly to S3 Tables. The result is scalable, serverless post-event data onboarding, as shown in the following figure.

Solution architecture for automated PDF processing workflow with S3 Tables, EventBridge scheduling, Step Functions Distributed Map

The data processing workflow as shown in the preceding diagram includes the following steps:

  1. A user uploads customer interest forms as scanned PDFs to an Amazon S3 bucket.
  2. An Amazon EventBridge Scheduler rule triggers at regular intervals, initiating a Step Functions workflow execution.
  3. The workflow execution activates a Step Functions Distributed Map state, which lists all PDF files uploaded to Amazon S3 since the previous run.
  4. The Distributed Map iterates over the list of objects and passes each object’s metadata (bucket, key, size, entity tag [ETag]) to a child workflow execution.
  5. For each object, the child workflow calls Amazon Textract with the provided bucket and key to extract raw text and relevant fields (name, email address, mailing address, interest area) from the PDF.
  6. The child workflow sends the extracted data to Amazon Data Firehose, which is configured to forward data to S3 Tables.
  7. Firehose batches the incoming data from the child workflow and writes it to S3 Tables at a preconfigured time interval of your choosing.

With data now structured and accessible in S3 Tables, users can easily analyze them using standard SQL queries with Amazon Athena or business intelligence like Amazon QuickSight.

The data-processing workflow

EventBridge Scheduler starts new Step Functions workflows at regular intervals. The timeline for this schedule is flexible. However, When setting up your schedule, make sure the frequency aligns with how far back your state machine is configured to look for PDFs. For example, if your state machine checks for PDFs from the past week, you’d want to schedule it to run weekly. The Step Functions workflow subsequently performs the following three steps (note that these steps are steps 4, 5, 6, and 7 in the preceding workflow diagram:

  1. Extract relevant user data from the PDFs.
  2. Send the extracted user data to Firehose.
  3. Write the data to S3 Tables in Apache Iceberg table format.

The following diagram illustrates this workflow.

Screenshot of AWS Step Function workflow execution showing processing pipeline from S3 ingenstion through Kinesis batch output

Let’s look at each step of the preceding workflow in more detail.

Extract relevant user data from PDF documents

Step Functions uses Distributed Map to process PDFs concurrently in parallel child workflows. It accepts input from JSON, JSONL, CSV, Parquet files, Amazon S3 manifest files stored in Amazon S3 (used to specify particular files for processing), or an Amazon S3 bucket prefix (allows iteration over file metadata for all objects under that prefix). The Step Functions automatically handles parallelization by splitting the dataset and running child workflows for each item, with the ItemBatcher field allowing to group multiple PDFs into a single child workflow execution (e.g., 10 PDFs per batch) to optimize performance and cost.

The following screenshot of the Step Functions console shows the configuration for Distributed Map. For example, we have configured Distributed Map to process 10 customer interest PDFs in a single child workflow.

A screenshot of AWS Step Functions console showing Distributed Map state configuration

The following image shows one example of these scanned PDFs, which includes the customer information that this post’s solution processes.

A screenshot showing sample PDF

Each child workflow then calls the Amazon Textract AnalyzeDocument API with specific queries to extract customer information.

{
  "Document": {
    "S3Object": {
      "Bucket": "<input PDFs bucket>",
      "Name": "{% $states.input.Key %}"
    }
  },
  "FeatureTypes": [
    "QUERIES"
  ],
  "QueriesConfig": {
    "Queries": [
      {
        "Alias": "full_name",
        "Text": "What is the customer's name?"
      },
      {
        "Alias": "phone_number",
        "Text": "What is the customer’s phone number?"
      },
      {
        "Alias": "mailing_address",
        "Text": "What is the customer’s mailing address?"
      },
      {
        "Alias": "interest",
        "Text": "What is the customer’s interest?"
      }
    ]
  }
}

The API analyzes each scanned PDF and returns a JSON structure containing the extracted customer information.

Send the extracted user data to Firehose

The child workflow then uses a Firehose PutRecordBatch API action with service integrations to queue the extracted customer information for further processing. The PutRecordBatch action request includes the Firehose stream name and the data records. The data records include a data blob from step 1 that contains extracted customer information, as shown in the following example.

{
  "DeliveryStreamName": "put_raw_form_data_100",
  "Records": [
    {
      "Data": "{\"full_name\":\"Anthony Ayala\",\"phone_number\":\"001-384-925-0701\",\"mailing_address\":\"38548 Joshua Wall Suite 974, East Heatherfort, OH 32669\",\"interest\":\"Fitness Trackers\",\"processed_date\":\"2025-05-01\"}"
    },
    {
      "Data": "{\"full_name\":\"Becky Williams\",\"phone_number\":\"+1-283-499-2466\",\"mailing_address\":\"227 King Forge Suite 241, East Nathanland, PR 05687\",\"interest\":\"Al Assistants\",\"processed_date\":\"2025-05-01\"}"
    }
  ]
}

Write the data to S3 Tables in Apache Iceberg table format

Firehose efficiently manages data buffering, format conversion, and reliable delivery to various destinations, including Apache Iceberg, raw files in Amazon S3, Amazon OpenSearch Service, or any of the other supported destinations. Apache Iceberg tables can be either self-managed in Amazon S3 or hosted in S3 Tables. Though self-managed Iceberg tables require manual optimization—such as compaction and snapshot expiration—S3 Tables automatically optimize storage for large-scale analytics workloads, improving query performance and reducing storage costs.

Firehose simplifies the process of streaming data by configuring a delivery stream, selecting a data source, and setting an Iceberg table as the destination. After you’ve set it up, the Firehose stream is ready to deliver data. The delivered data can be queried from S3 Tables by using Athena, as shown in the following screenshot of the Athena console.

A screenshot of the Athena console showing a query to select the data we just uploaded

The query results include all processed customer data from the PDFs, as shown in the following screenshot.

A screenshot of the Athena console showing the results of the query we just ran

This integration demonstrates a powerful, code-free solution for transforming raw PDF forms into enriched, queryable data in an Iceberg table. You can use these data for further analysis.

Conclusion

In this post, we showed how to build a scalable, serverless solution for processing PDF documents and exporting the extracted data to S3 Tables by using Step Functions Distributed Map. This architecture offers several key benefits such as reliability, cost-effectiveness, visibility, and maintainability. By leveraging AWS services such as Step Functions, Amazon Textract, Firehose, and S3 Tables, companies can automate their document processing workflows while ensuring optimal performance and operational excellence. This solution can be adapted for various use cases beyond customer interest forms, such as invoice processing, application forms, or any scenario requiring structured data extraction from documents at scale.

Though this example focuses on processing PDF data and writing to S3 Tables, Distributed Map can handle various input sources including JSON, JSONL, CSV, and Parquet files in Amazon S3; items in Amazon DynamoDB tables; Athena query results; and all paginated AWS List APIs. Similarly, through Step Functions service integrations, you can write results to multiple destinations such as DynamoDB tables by using the PutItem service integration.

To get started with this solution, see the associated GitHub repository for deployment instructions and sample code.

Scaling cluster manager and admin APIs in Amazon OpenSearch Service

Post Syndicated from Rajiv Kumar Vaidyanathan original https://aws.amazon.com/blogs/big-data/scaling-cluster-manager-and-admin-apis-in-amazon-opensearch-service/

Amazon OpenSearch Service is a managed service that makes it simple to deploy, secure, and operate OpenSearch clusters at scale in the AWS Cloud. A typical OpenSearch cluster is comprised of cluster manager, data, and coordinator nodes. It is recommended to have three cluster manager nodes, and one of them will be elected as a leader node.

Amazon OpenSearch Service introduced support for 1,000-node OpenSearch Service clusters capable of handling 500,000 shards with OpenSearch Service version 2.17. For large clusters, we have identified bottlenecks in admin API interactions (with the leader) and introduced improvements in OpenSearch Service version 2.17. These improvements have helped OpenSearch Service to publish cluster metrics and monitor at same frequency for large clusters while maintaining the optimal resource usage (less than 10% CPU and less than 75% JVM usage) on the leader node (16 core CPU with 64 GB JVM heap). It has also ensured that metadata management can be performed on large clusters with predictable latency without destabilizing the leader node.

General monitoring of an OpenSearch node using health check and statistics API endpoints doesn’t cause visible load to the leader. But as the number of nodes increase in the cluster, the volume of these monitoring calls also increases proportionally. The increase in the call volume coupled with the less optimal implementation of these endpoints overwhelms the leader node, resulting in stability issues. In this post, we demonstrate the different bottlenecks that were identified and the corresponding solutions that were implemented in OpenSearch Service to scale cluster manager for large cluster deployments. These optimizations are available to all new domains or existing domains upgraded to OpenSearch Service versions 2.17 or above.

Cluster state

To understand the various bottlenecks with the cluster manager, let’s examine the cluster state, whose management is the core operation of the leader. The cluster state contains the following key metadata information:

  • Cluster settings
  • Index metadata, which includes index settings, mappings, and alias
  • Routing table and shard metadata, which contains details of shard allocation to nodes
  • Node information and attributes
  • Snapshot information, custom metadata, and so on

Node, index, and shard are managed as first-class entities by the cluster manager and contain information such as identifier, name, and attributes for each of their instances.

The following screenshots are from a sample cluster state for a cluster with three cluster manager and three data nodes. The cluster has a single index (sample-index1) with one primary and two replicas.

Cluster metadata showing index and shard configuration

Nodes metadata

As shown in the screenshots, the number of entries in the cluster state is as follows:

  • IndexMetadata (metadata#indices) has entries equal to the total number of indexes
  • RoutingTable (routing_table) has entries equal to the number of indexes multiplied by the number of shards per index
  • NodeInfo (nodes) has entries equal to the number of nodes in the cluster

The size of a sample cluster state with six nodes, one index, and three shards is around 15 KB (size of JSON response from the API). Consider a cluster with 1,000 nodes, which has 10,000 indexes with an average of 50 shards per index. The cluster state would have 10,000 entries for IndexMetadata, 500,000 entries for RoutingTable, and 1,000 entries for NodeInfo.

Bottleneck 1: Cluster state communication

OpenSearch provides admin APIs as a REST endpoint for users to manage and configure the cluster metadata. Admin API requests are handled by either coordinator node (or) by data node if the cluster does not have dedicated coordinator node provisioned. You can use admin APIs to check cluster health, modify settings, retrieve statistics, and more. Some of the examples are the CAT, Cluster Settings, and Node Stats APIs.

The following diagram illustrates the admin API control flow.

Admin API Request Flow

Let’s consider a Read API request to fetch information about the cluster settings.

  1. The user makes the call to the HTTP endpoint backed by the coordinator node.
  2. The coordinator node initiates an internal transport call to the leader of the cluster.
  3. The transport handler in the leader node performs a filter and selection of metadata based on the input request from the latest cluster state.
  4. The processed cluster state is then returned back to the coordinating node, which then generates the response and finishes the request processing.

The cluster state processing on the nodes is shown in the following diagram.

Request Processing using Cluster State

As discussed earlier, most of the admin read requests require the latest cluster state and the node which processes the API request and makes a _cluster/state call to the leader. In a cluster setup of 1,000 nodes and 500,000 shards, the size of the cluster state would be around 250 MB. This can overload leader and cause the following issues:

  • CPU usage increases on the leader due to simultaneous admin calls because the leader has to vend the latest state to many coordinating nodes in the cluster simultaneously.
  • The heap memory consumption of the cluster state can grow to multiples of 100 MB depending upon the number of index mappings and settings configured by the user. It causes JVM memory pressure to build on the leader, causing frequent garbage collection pauses.
  • Repeated serialization and transfer of the large cluster state causes transport worker threads to be busy on the leader node, potentially causing delays and timeouts of further requests.

The leader node sends periodic ping requests to follower nodes and requires transport threads to process the responses. Because the number of threads serving the transport channel is limited (defaults to the number of processor cores), the responses are not processed in a timely fashion. The leader-follower health checks in the cluster get timed out, thereby causing a spiral effect of nodes leaving the cluster and more shard recoveries being initiated by the leader.

Solution: Latest local cluster state

Cluster state is versioned using two long fields: term and version. The term number is incremented whenever a new leader is elected, and the version number is incremented with every metadata update. Given that the latest cluster state is cached on all the nodes, it can be used to serve the admin API request if it is up-to-date with the leader. To check the freshness of the cached copy, a light-weight transport API is introduced, which fetches only the term and version corresponding to the latest cluster state from leader. The request-coordinating node matches it with the local term and version, and if they’re the same, it uses the local cluster sate to serve the admin API read request. If the cached cluster state is out of sync, the node makes a subsequent transport call to fetch the latest cluster state and then serves the incoming API request. This offloads the responsibility of serving read requests to the coordinating node, thereby reducing the load on the leader node.

Cluster state processing on the nodes after the optimization is shown in the following diagram.

Optimized Request Processing

Term-version checks for cluster state processing are now used by 17 read APIs across the _cat and _cluster APIs in OpenSearch.

Impact: Less CPU resource usage on leader

From our load tests, we observed at least 50% reduction in CPU usage without a change in the API latency due to the aforementioned improvement. The load test was performed on an OpenSearch cluster consisting of 3 cluster manager nodes (8 cores each), 5 data nodes (64 cores each), and 25,000 shards with a cluster state size of around 50 MB. The workload consists of the following admin APIs invoked, with periodicity mentioned in the following table:

  • /_cluster/state
  • /_cat/indices
  • /_cat/shards
  • /_cat/allocation
Request Count / 5 minutes CPU (max)
Existing Setup With Optimization
3000 14% 7%
6000 20% 10%
9000 28% 12%

Bottleneck 2: Scatter-gather nature of statistics admin APIs

The next group of admin APIs are used to fetch the statistics information of the cluster. These APIs include _cat/indices, _cat/shards, _cat/segments, _cat/nodes, _cluster/stats, and _nodes/stats, to name a few. Unlike metadata, which is managed by the leader, the statistics information is distributed across the data nodes in the cluster.

For example, consider the response to the _cat/indices API for the index sample-index1:

[
  {
    "health": "green",
    "status": "open",
    "index": "sample-index1",
    "uuid": "QrWpe7aDTRGklmSp5joKyg",
    "pri": "1",
    "rep": "2",
    "docs.count": "30",
    "docs.deleted": "0",
    "store.size": "624b",
    "pri.store.size": "208b"
  }
]

The values for fields docs.count, docs.deleted , store.size, and pri.store.size are fetched from the data nodes, which have the corresponding shards, and are then aggregated by the coordinating node. To compute the preceding response for sample-index1, the coordinator node collects the statistics responses from three data nodes hosting one primary and two replica shards, respectively.

Every data node in the cluster collects statistics related to operations such as indexing, search, merges, and flushes for the shards it manages. Every shard in the cluster has about 150 indices metrics tracked across 20 metric groups.

The response from the data node to coordinator contains all the shard statistics of the index and not just the ones (docs and store stats) requested by the user. The response size of stats returned from data node for a single shard is around 4 KB. The following diagram illustrates the stats data flow among nodes in a cluster.

Stats API Request Flow

For a cluster with 500,000 shards, the coordinator node needs to retrieve stats responses from different nodes whose sizes sum to around 2.5 GB. The retrieval of such large response sizes can cause the following issues:

  • High network throughput volume between nodes.
  • Increased memory pressure because statistics responses returned by data nodes are accumulated in memory of the coordinator node before constructing the user-facing response.

The memory pressure can cause a circuit breaker of the coordinator node to trip, resulting in 429 TOO MANY REQUEST responses. It also results in an increase in CPU utilization on the coordinator node due to garbage collection cycles being triggered to reclaim the heap used for stats requests. The overloading of the coordinator node to fetch statistics information for admin requests can potentially result in rejecting critical API requests such as health check, search, and indexing, resulting in a spiral effect of failures.

Solution: Local aggregation and filtering

Because the admin API returns only the user-requested stats in the response, it is not required by data nodes to send the entire shard-level stats because it’s not requested by the user. We have now introduced stats aggregation at transport action so each data node aggregates the stats locally and then responds back to the coordinator node. Additionally, data nodes support filtering of statistics so only specific shard stats, as requested by the user, can be returned to the coordinator. This results in reduced compute and memory on coordinator nodes because they now work with responses that are far smaller.

The following output is the shard stats returned by a data node to the coordinator node after local aggregation by index. The response is also filtered based on user-requested statistics. The response contains only docs and store metrics aggregated by index for shards present on the node.

Stats Received on Coordinator after Optimization

Impact: Faster response time

The following table shows the latency for health and stats API endpoints in a large cluster. These results are for a cluster size of 3 cluster manager nodes, 1,000 data nodes, and 500,000 shards. As explained in the following pull request, the optimization to pre-compute statistics prior to sending response helps reduce response size and improve latency.

API Response Latency
Existing Setup With Optimization
_cluster/stats 15s 0.65s
_nodes/stats 13.74s 1.69s
_cluster/health 0.56s 0.15s

Bottleneck 3: Long-running stats request

With admin APIs, users can specify the timeout parameter as part of the request. This helps the client fail fast if requests are taking more time to be processed due to an overloaded leader or data node. However, the coordinator node continues to process the request and initiate internal transport requests to data nodes even after the user’s request gets disconnected. This is wasteful work and causes unnecessary load on the cluster because the response from the data node is discarded by the coordinator after the request has timed out. No mechanism exists for the coordinator to track that the request has been cancelled by the user and further downstream transport calls don’t need to be attempted.

Solution: Cancellation at transport layer

To prevent long-running transport requests for admin APIs and reduce the overhead on the already overwhelmed data nodes, cancellation has been implemented at the transport layer. This is now used by the coordinator to cancel the transport requests to data nodes after the user-specified timeout expires.

Impact: Fail fast without cascading failures

The _cat/shards API fails gracefully if the leader is overloaded in case of large clusters. The API returns a timeout response to the user without issuing broadcast calls to data nodes.

Bottleneck 4: Huge response size

Let’s now look at challenges with the popular _cat APIs. Historically, CAT APIs didn’t support pagination because the metadata wasn’t expected to grow to tens of thousands in size when it was designed. This assumption no longer holds for large clusters and can cause compute and memory spikes while serving these APIs.

Solution: Paginated APIs

After careful deliberations with the community, we introduced a new set of paginated list APIs for metadata retrieval. The APIs _list/indices and _list/shards are pagination counterparts to _cat/indices and _cat/shards. The _list APIs maintain pagination stability, so that a paginated dataset maintains order and consistency even when a new index is added or an existing index is removed. This is achieved by using a combination of index creation timestamps and index names as page tokens.

Impact: Bounded response time

_list/shards can now successfully return paginated responses for a cluster with 500,000 shards without getting timed out. Fixed response sizes facilitate faster data retrieval without overwhelming the cluster for large datasets.

Conclusion

Admin API’s are critical for observability and metadata management of OpenSearch domains. Admin APIs, if not designed properly, introduce bottlenecks in the system and impacts the performance of OpenSearch domains. The improvements made for these APIs in version 2.17 have performance gains for all customers of OpenSearch service irrespective of whether it is large-sized (1,000 nodes), mid-sized (200 nodes), or small-sized (20 nodes). It ensures that elected cluster manager node is stable even when the API’s are exercised for domains with large metadata size. OpenSearch is an open source, community-driven software. The foundational pieces of APIs such as pagination, cancellation, and local aggregation are extensible and can be used for other APIs.

If you would like to contribute to OpenSearch, open up a GitHub issue and let us know your thoughts. You could get started with these open PR’s in Github [PR1] [PR2] [PR3] [PR4].


About the authors

Rajiv Kumar

Rajiv Kumar

Rajiv is a Senior Software Engineer working on OpenSearch at Amazon Web Services. He is interested in solving distributed system problems and an active contributor to OpenSearch.

Shweta Thareja

Shweta Thareja

Shweta is a Principal Engineer working on Amazon OpenSearch Service. She is interested in building distributed and autonomous systems. She is a maintainer and an active contributor to OpenSearch.