I’ve been at AWS for more than four years, and I’ve enjoyed every minute of it! I started as a consultant in Professional Services, and I’ve been a Security Solutions Architect for around three years.
How do you explain your job to your non-tech friends?
Well, my mother doesn’t totally understand my role, and she’s been known to tell her friends that I’m the cable company technician that installs your internet modem and router. I usually tell my non-tech friends that I help AWS customers protect their sensitive data. If I mention cryptography, I typically only get asked questions about cryptocurrency—which I’m not qualified to answer. If someone asks what cryptography is, I usually say it’s protecting data by using mathematics.
How did you get started in data protection and cryptography? What about it piqued your interest?
I originally went to school to become a network engineer, but I discovered that moving data packets from point A to point B wasn’t as interesting to me as securing those data packets. Early in my career, I was an intern at an insurance company, and I had a mentor who set up ethnical hacking lessons for me—for example, I’d come into the office and he’d have a compromised workstation preconfigured. He’d ask me to do an investigation and determine how the workstation was compromised and what could be done to isolate it and collect evidence. Other times, I’d come in and find my desk cabinets were locked with a padlock, and he wanted me to pick the lock. Security is particularly interesting because it’s an ever-evolving field, and I enjoy learning new things.
What’s been the most dramatic change you’ve seen in the data protection landscape?
One of the changes that I’ve been excited to see is an emphasis on encrypting everything. When I started my career, we’d often have discussions about encryption in the context of tradeoffs. If we needed to encrypt sensitive data, we’d have a conversation with application teams about the potential performance impact of encryption and decryption operations on their systems (for example, their databases), when to schedule downtime for the application to encrypt the data or rotate the encryption keys protecting the data, how to ensure the durability of their keys and make sure they didn’t lose data, and so on.
When I talk to customers about encryption on AWS today—of course, it’s still useful to talk about potential performance impact—but the conversation has largely shifted from “Should I encrypt this data?” to “How should I encrypt this data?” This is due to services such as AWS Key Management Service (AWS KMS) making it simpler for customers to manage encryption keys and encrypt and decrypt data in their applications with minimal performance impact or application downtime. AWS KMS has also made it simple to enable encryption of sensitive data—with over 120 AWS services integrated with AWS KMS, and services such as Amazon Simple Storage Service (Amazon S3) encrypting new S3 objects by default.
You are a frequent contributor to the AWS Security Blog. What were some of your recent posts about?
You are speaking in a couple of sessions at AWS re:Invent; what will your sessions focus on? What do you hope attendees will take away from your session?
I’m delivering two sessions at re:Invent this year. The first is a chalk talk, Centrally manage application secrets with AWS Secrets Manager (SEC221), that I’m delivering with Ritesh Desai, who is the General Manager of Secrets Manager. We’re discussing how you can securely store and manage secrets in your workloads inside and outside of AWS. We will highlight some recommended practices for managing secrets, and answer your questions about how Secrets Manager integrates with services such as AWS KMS to help protect application secrets.
The second session is also a chalk talk, Securely modernize payment applications with AWS (SEC326). I’m delivering this talk with Mark Cline, who is the Senior Product Manager of AWS Payment Cryptography. We will walk through an example scenario on creating a new payment processing application. We will discuss how to use AWS Payment Cryptography, as well as other services such as AWS Lambda, to build a simple architecture to help process and secure credit card payment data. We will also include common payment industry use cases such as tokenization of sensitive data, and how to include basic anti-fraud detection, in our example app.
What are you currently working on that you’re excited about?
My re:Invent sessions are definitely something that I’m excited about. Otherwise, I spend most of my time talking to customers about AWS Cryptography services such as AWS KMS, AWS Secrets Manager, and AWS Private Certificate Authority. I also lead a program at AWS that enables our subject matter experts to create and publish videos to demonstrate new features of AWS Security Services. I like helping people create videos, and I hope that our videos provide another mechanism for viewers who prefer information in a video format. Visual media can be more inclusive for customers with certain disabilities or for neurodiverse customers who find it challenging to focus on written text. Plus, you can consume videos differently than a blog post or text documentation. If you don’t have the time or desire to read a blog post or AWS public doc, you can listen to an instructional video while you work on other tasks, eat lunch, or take a break. I invite folks to check out the AWS Security Services Features Demo YouTube video playlist.
Is there something you wish customers would ask you about more often?
I always appreciate when customers provide candid feedback on our services. AWS is a customer-obsessed company, and we build our service roadmaps based on what our customers tell us they need. You should feel comfortable letting AWS know when something could be easier, more efficient, or less expensive. Many customers I’ve worked with have provided actionable feedback on our services and influenced service roadmaps, just by speaking up and sharing their experiences.
How about outside of work, any hobbies?
I have two toddlers that keep me pretty busy, so most of my hobbies are what they like to do. So I tend to spend a lot of time building elaborate toy train tracks, pushing my kids on the swings, and pretending to eat wooden toy food that they “cook” for me. Outside of that, I read a lot of fiction and indulge in binge-worthy TV.
If you have feedback about this post, submit comments in the Comments section below.
Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.
Stream data processing allows you to act on data in real time. Real-time data analytics can help you have on-time and optimized responses while improving the overall customer experience.
Data streaming workloads often require data in the stream to be enriched via external sources (such as databases or other data streams). Pre-loading of reference data provides low latency and high throughput. However, this pattern may not be suitable for certain types of workloads:
Reference data updates with high frequency
The streaming application needs to make an external call to compute the business logic
Accuracy of the output is important and the application shouldn’t use stale data
Cardinality of reference data is very high, and the reference dataset is too big to be held in the state of the streaming application
For example, if you’re receiving temperature data from a sensor network and need to get additional metadata of the sensors to analyze how these sensors map to physical geographic locations, you need to enrich it with sensor metadata data.
Apache Flink is a distributed computation framework that allows for stateful real-time data processing. It provides a single set of APIs for building batch and streaming jobs, making it easy for developers to work with bounded and unbounded data. Amazon Managed Service for Apache Flink (successor to Amazon Kinesis Data Analytics) is an AWS service that provides a serverless, fully managed infrastructure for running Apache Flink applications. Developers can build highly available, fault tolerant, and scalable Apache Flink applications with ease and without needing to become an expert in building, configuring, and maintaining Apache Flink clusters on AWS.
You can use several approaches to enrich your real-time data in Amazon Managed Service for Apache Flink depending on your use case and Apache Flink abstraction level. Each method has different effects on the throughput, network traffic, and CPU (or memory) utilization. For a general overview of data enrichment patterns, refer to Common streaming data enrichment patterns in Amazon Managed Service for Apache Flink.
This post covers how you can implement data enrichment for near-online streaming events with Apache Flink and how you can optimize performance. To compare the performance of the enrichment patterns, we ran performance testing based on synthetic data. The result of this test is useful as a general reference. It’s important to note that the actual performance for your Flink workload will depend on various and different factors, such as API latency, throughput, size of the event, and cache hit ratio.
We discuss three enrichment patterns, detailed in the following table.
.
Synchronous Enrichment
Asynchronous Enrichment
Synchronous Cached Enrichment
Enrichment approach
Synchronous, blocking per-record requests to the external endpoint
Non-blocking parallel requests to the external endpoint, using asynchronous I/O
Frequently accessed information is cached in the Flink application state, with a fixed TTL
Data freshness
Always up-to-date enrichment data
Always up-to-date enrichment data
Enrichment data may be stale, up to the TTL
Development complexity
Simple model
Harder to debug, due to multi-threading
Harder to debug, due to relying on Flink state
Error handling
Straightforward
More complex, using callbacks
Straightforward
Impact on enrichment API
Max: one request per message
Max: one request per message
Reduce I/O to enrichment API (depends on cache TTL)
Application latency
Sensitive to enrichment API latency
Less sensitive to enrichment API latency
Reduce application latency (depends on cache hit ratio)
Other considerations
none
none
Customizable TTL.
Only synchronous implementation as of Flink 1.17
Result of the comparative test (Throughput)
~350 events per second
~2,000 events per second
~28,000 events per second
Solution overview
For this post, we use an example of a temperature sensor network (component 1 in the following architecture diagram) that emits sensor information, such as temperature, sensor ID, status, and the timestamp this event was produced. These temperature events get ingested into Amazon Kinesis Data Streams (2). Downstream systems also require the brand and country code information of the sensors, in order to analyze, for example, the reliability per brand and temperature per plant side.
Based on the sensor ID, we enrich this sensor information from the Sensor Info API (3), which provide us with information of the brand, location, and an image. The resulting enriched stream is sent to another Kinesis data stream and can then be analyzed in an Amazon Managed Service for Apache Flink Studio notebook (4).
Prerequisites
To get started with implementing near-online data enrichment patterns, you can clone or download the code from the GitHub repository. This repository implements the Flink streaming application we described. You can find the instructions on how to set up Flink in either Amazon Managed Service for Apache Flink or other available Flink deployment options in the README.md file.
If you want to learn how these patterns are implemented and how to optimize performance for your Flink application, you can simply follow along with this post without deploying the samples.
Project overview
The project is structured as follows:
docs/                               -- Contains project documentation
src/
├── main/java/...                   -- Contains all the Flink application code
│   ├── ProcessTemperatureStream    -- Main class that decides on the enrichment strategy
│   ├── enrichment.                 -- Contains the different enrichment strategies (sync, async and cached)
│   ├── event.                      -- Event POJOs
│   ├── serialize.                  -- Utils for serialization
│   └── utils.                      -- Utils for Parameter parsing
└── test/                           -- Contains all the Flink testing code
The main method in the ProcessTemperatureStream class sets up the run environment and either takes the parameters from the command line, if it’s is a local environment, or uses the application properties from Amazon Managed Service for Apache Flink. Based on the parameter EnrichmentStrategy, it decides which implementation to pick: synchronous enrichment (default), asynchronous enrichment, or cached enrichment based on the Flink concept of KeyedState.
public static void main(String[] args) throws Exception {
    StreamExecutionEnvironment env = StreamExecutionEnvironment.getExecutionEnvironment();
     ParameterTool parameter = ParameterToolUtils.getParameters(args, env);

    String strategy = parameter.get("EnrichmentStrategy", "SYNC");
     switch (strategy) {
         case "SYNC":
             new SyncProcessTemperatureStreamStrategy().run(env, parameter);
             break;
         case "ASYNC":
             new AsyncProcessTemperatureStreamStrategy().run(env, parameter);
             break;
        case "CACHED":
             new CachedProcessTemperatureStreamStrategy().run(env, parameter);
             break;
         default:
             throw new InvalidParameterException("Please choose one of the existing enrichment strategies (SYNC|ASYNC|CACHED)");
     }
}
We go over the three approaches in the following sections.
Synchronous data enrichment
When you want to enrich your data from an external provider, you can use synchronous per-record lookup. When your Flink application processes an incoming event, it makes an external HTTP call and after sending every request, it has to wait until it receives the response.
As Flink processes events synchronously, the thread that is running the enrichment is blocked until it receives the HTTP response. This results in the processor staying idle for a significant period of processing time. On the other hand, the synchronous model is easier to design, debug, and trace. It also allows you to always have the latest data.
It can be integrated into your streaming application as such:
The implementation of the enrichment function looks like the following code:
public class SyncEnrichmentFunction extends RichMapFunction<Temperature, EnrichedTemperature> {

    // Setup of HTTP client and ObjectMapper

    @Override
    public EnrichedTemperature map(Temperature temperature) throws Exception {
        String url = this.getRequestUrl + temperature.getSensorId();

        // Retrieve response from sensor info API
        Response response = client
                .prepareGet(url)
                .execute()
                .toCompletableFuture()
                .get();

        // Parse the sensor info
        SensorInfo sensorInfo = parseSensorInfo(response.getResponseBody());

        // Merge the temperature sensor data and sensor info data
        return getEnrichedTemperature(temperature, sensorInfo);
    }

    // ...
}
To optimize the performance for synchronous enrichment, you can use the KeepAlive flag because the HTTP client will be reused for multiple events.
For applications with I/O-bound operators (such as external data enrichment), it can also make sense to increase the application parallelism without increasing the resources dedicated to the application. You can do this by increasing the ParallelismPerKPU setting of the Amazon Managed Service for Apache Flink application. This configuration describes the number of parallel subtasks an application can perform per Kinesis Processing Unit (KPU), and a higher value of ParallelismPerKPU can lead to full utilization of KPU resources. But keep in mind that increasing the parallelism doesn’t work in all cases, such as when you are consuming from sources with few shards or partitions.
In our synthetic testing with Amazon Managed Service for Apache Flink, we saw a throughput of approximately 350 events per second on a single KPU with 4 parallelism per KPU and the default settings.
Asynchronous data enrichment
Synchronous enrichment doesn’t take full advantage of computing resources. That’s because Fink waits for HTTP responses. But Flink offers asynchronous I/O for external data access. This allows you to enrich the stream events asynchronously, so it can send a request for other elements in the stream while it waits for the response for the first element and requests can be batched for greater efficiency.
While using this pattern, you have to decide between unorderedWait (where it emits the result to the next operator as soon as the response is received, disregarding the order of the elements on the stream) and orderedWait (where it waits until all inflight I/O operations complete, then sends the results to the next operator in the same order as the original elements were placed on the stream). When your use case doesn’t require event ordering, unorderedWait provides better throughput and less idle time. Refer to Enrich your data stream asynchronously using Amazon Managed Service for Apache Flink to learn more about this pattern.
The asynchronous enrichment can be added as follows:
The enrichment function works similar as the synchronous implementation. It first retrieves the sensor info as a Java Future, which represents the result of an asynchronous computation. As soon as it’s available, it parses the information and then merges both objects into an EnrichedTemperature:
public class AsyncEnrichmentFunction extends RichAsyncFunction<Temperature, EnrichedTemperature> {

    // Setup of HTTP client and ObjectMapper

    @Override
    public void asyncInvoke(final Temperature temperature, final ResultFuture<EnrichedTemperature> resultFuture) {
        String url = this.getRequestUrl + temperature.getSensorId();

        // Retrieve response from sensor info API
        Future<Response> future = client
                .prepareGet(url)
                .execute();
        CompletableFuture
                .supplyAsync(() -> {
                    try {
                        Response response = future.get();

                        // Parse the sensor info as soon as it is available
                        return parseSensorInfo(response.getResponseBody());
                    } catch (Exception e) {
                        return null;
                    }
                })
                .thenAccept((SensorInfo sensorInfo) ->

                    // Merge the temperature sensor data and sensor info data
                    resultFuture.complete(getEnrichedTemperature(temperature, sensorInfo)));
    }

    // ...
}
In our testing with Amazon Managed Service for Apache Flink, we saw a throughput of 2,000 events per second on a single KPU with 2 parallelism per KPU and the default settings.
Synchronous cached data enrichment
Although numerous operations in a data flow focus on individual events independently, such as event parsing, there are certain operations that retain information across multiple events. These operations, such as window operators, are referred to as stateful due to their ability to maintain state.
The keyed state is stored within an embedded key-value store, conceptualized as a part of Flink’s architecture. This state is partitioned and distributed in conjunction with the streams that are consumed by the stateful operators. As a result, access to the key-value state is limited to keyed streams, meaning it can only be accessed after a keyed or partitioned data exchange, and is restricted to the values associated with the current event’s key. For more information about the concepts, refer to Stateful Stream Processing.
You can use the keyed state for frequently accessed information that doesn’t change often, such as the sensor information. This will not only allow you to reduce the load on downstream resources, but also increase the efficiency of your data enrichment because no round-trip to an external resource for already fetched keys is necessary and there’s also no need to recompute the information. But keep in mind that Amazon Managed Service for Apache Flink stores transient data in a RocksDB backend, which adds a latency to retrieving the information. But because RocksDB is local to the node processing the data, this is faster than reaching out to external resources, as you can see in the following example.
To use keyed streams, you have to partition your stream using the .keyBy(...) method, which assures that events for the same key, in this case sensor ID, will be routed to the same worker. You can implement it as follows:
We are using the sensor ID as the key to partition the stream and later enrich it. This way, we can then cache the sensor information as part of the keyed state. When picking a partition key for your use case, choose one that has a high cardinality. This leads to an even distribution of events across different workers.
To store the sensor information, we use the ValueState. To configure the state management, we have to describe the state type by using the TypeHint. Additionally, we can configure how long a certain state will be cached by specifying the time-to-live (TTL) before the state will be cleaned up and has to retrieved or recomputed again.
public class CachedEnrichmentFunction extends KeyedProcessFunction<String, Temperature, EnrichedTemperature> {

    // Setup of HTTP client and ObjectMapper...

    private transient ValueState<SensorInfo> cachedSensorInfoLight;

    @Override
    public void open(Configuration configuration) throws Exception {
        // Initialize HTTP client

        ValueStateDescriptor<SensorInfo> descriptor =
                new ValueStateDescriptor<>("sensorInfo", TypeInformation.of(new TypeHint<>()}));

        StateTtlConfig ttlConfig = StateTtlConfig
                .newBuilder(Time.seconds(this.ttl))
                .setUpdateType(StateTtlConfig.UpdateType.OnCreateAndWrite)
                .setStateVisibility(StateTtlConfig.StateVisibility.ReturnExpiredIfNotCleanedUp)
                .build();
        descriptor.enableTimeToLive(ttlConfig);

        cachedSensorInfoLight = getRuntimeContext().getState(descriptor);
    }

    // ...
}
As of Flink 1.17, access to the state is not possible in asynchronous functions, so the implementation must be synchronous.
It first checks if the sensor information for this particular key exists; if so, it gets enriched. Otherwise, it retrieves the sensor information, parses it, and then merges both objects into an EnrichedTemperature:
public class CachedEnrichmentFunction extends KeyedProcessFunction<String, Temperature, EnrichedTemperature> {

    // Setup of HTTP client, ObjectMapper and ValueState

    @Override
    public void processElement(Temperature temperature, KeyedProcessFunction<String, Temperature, EnrichedTemperature>.Context ctx, Collector<EnrichedTemperature> out) throws Exception {
        SensorInfo sensorInfoCachedEntry = cachedSensorInfoLight.value();

        // Check if sensor info is cached
        if (sensorInfoCachedEntry != null) {
            out.collect(getEnrichedTemperature(temperature, sensorInfoCachedEntry));
        } else {
            String url = this.getRequestUrl + temperature.getSensorId();

            // Retrieve response from sensor info API
            Response response = client
                    .prepareGet(url)
                    .execute()
                    .toCompletableFuture()
                    .get();

            // Parse the sensor info
            SensorInfo sensorInfo = parseSensorInfo(response.getResponseBody());

            // Cache the sensor info
            cachedSensorInfoLight.update(sensorInfo);

            // Merge the temperature sensor data and sensor info data
            out.collect(getEnrichedTemperature(temperature, sensorInfo));
        }
    }

    // ...
}
In our synthetic testing with Amazon Managed Service for Apache Flink, we saw a throughput of 28,000 events per second on a single KPU with 4 parallelism per KPU and the default settings.
You can also see the impact and reduced load on the downstream sensor API.
Test your workload on Amazon Managed Service for Apache Flink
This post compared different approaches to run an application on Amazon Managed Service for Apache Flink with 1 KPU. Testing with a single KPU gives a good performance baseline that allows you to compare the enrichment patterns without generating a full-scale production workload.
It’s important to understand that the actual performance of the enrichment patterns depends on the actual workload and other external systems the Flink application interacts with. For example, performance of cached enrichment may vary with the cache hit ratio. Synchronous enrichment may behave differently depending on the response latency of the enrichment endpoint.
To evaluate which approach best suits your workload, you should first perform scaled-down tests with 1 KPU and a limited throughput of realistic data, possibly experimenting with different values of Parallelism per KPU. After you identify the best approach, it’s important to test the implementation at full scale, with real data and integrating with real external systems, before moving to production.
Summary
This post explored different approaches to implement near-online data enrichment using Flink, focusing on three communication patterns: synchronous enrichment, asynchronous enrichment, and caching with Flink KeyedState.
We compared the throughput achieved by each approach, with caching using Flink KeyedState being up to 14 times faster than using asynchronous I/O, in this particular experiment with synthetic data. Furthermore, we delved into optimizing the performance of Apache Flink, specifically on Amazon Managed Service for Apache Flink. We discussed strategies and best practices to maximize the performance of Flink applications in a managed environment, enabling you to fully take advantage of the capabilities of Flink for your near-online data enrichment needs.
Overall, this overview offers insights into different data enrichment patterns, their performance characteristics, and optimization techniques when using Apache Flink, particularly in the context of near-online data enrichment scenarios and on Amazon Managed Service for Apache Flink.
We welcome your feedback. Please leave your thoughts and questions in the comments section.
About the authors
Luis Morales works as Senior Solutions Architect with digital-native businesses to support them in constantly reinventing themselves in the cloud. He is passionate about software engineering, cloud-native distributed systems, test-driven development, and all things code and security.
Lorenzo Nicora works as Senior Streaming Solution Architect helping customers across EMEA. He has been building cloud-native, data-intensive systems for several years, working in the finance industry both through consultancies and for fin-tech product companies. He leveraged open source technologies extensively and contributed to several projects, including Apache Flink.
In the AWS Security Profile series, we feature the people who work in Amazon Web Services (AWS) Security and help keep our customers safe and secure. This interview is with Tom Scholl, VP and Distinguished Engineer for AWS.
What do you do in your current role and how long have you been at AWS?
I’m currently a vice president and distinguished engineer in the infrastructure organization at AWS. My role includes working on the AWS global network backbone, as well as focusing on denial-of-service detection and mitigation systems. I’ve been with AWS for over 12 years.
What initially got you interested in networking and how did that lead you to the anti-abuse and distributed denial of service (DDoS) space?
My interest in large global network infrastructure started when I was a teenager in the 1990s. I remember reading a magazine at the time that cataloged all the large IP transit providers on the internet, complete with network topology maps and sizes of links. It inspired me to want to work on the engineering teams that supported that. Over time, I was fortunate enough to move from working at a small ISP to a telecom carrier where I was able to work on their POP and backbone designs. It was there that I learned about the internet peering ecosystem and started collaborating with network operators from around the globe.
For the last 20-plus years, DDoS was always something I had to deal with to some extent. Namely, from the networking lens of preventing network congestion through traffic-engineering and capacity planning, as well as supporting the integration of DDoS traffic scrubbers into network infrastructure.
About three years ago, I became especially intrigued by the network abuse and DDoS space after using AWS network telemetry to observe the size of malicious events in the wild. I started to be interested in how mitigation could be improved, and how to break down the problem into smaller pieces to better understand the true sources of attack traffic. Instead of merely being an observer, I wanted to be a part of the solution and make it better. This required me to immerse myself into the domain, both from the perspective of learning the technical details and by getting hands-on and understanding the DDoS industry and environment as a whole. Part of how I did this was by engaging with my peers in the industry at other companies and absorbing years of knowledge from them.
How do you explain your job to your non-technical friends and family?
I try to explain both areas that I work on. First, that I help build the global network infrastructure that connects AWS and its customers to the rest of the world. I explain that for a home user to reach popular destinations hosted on AWS, data has to traverse a series of networks and physical cables that are interconnected so that the user’s home computer or mobile phone can send packets to another part of the world in less than a second. All that requires coordination with external networks, which have their own practices and policies on how they handle traffic. AWS has to navigate that complexity and build and operate our infrastructure with customer availability and security in mind. Second, when it comes to DDoS and network abuse, I explain that there are bad actors on the internet that use DDoS to cause impairment for a variety of reasons. It could be someone wanting to disrupt online gaming, video conferencing, or regular business operations for any given website or company. I work to prevent those events from causing any sort of impairment and trace back the source to disrupt that infrastructure launching them to prevent it from being effective in the future.
Recently, you were awarded the J.D. Falk Award by the Messaging Malware Mobile Anti-Abuse Working Group (M3AAWG) for IP Spoofing Mitigation. Congratulations! Please tell us more about the efforts that led to this.
Basically, there are three main types of DDoS attacks we observe: botnet-based unicast floods, spoofed amplification/reflection attacks, and proxy-driven HTTP request floods. The amplification/reflection aspect is interesting because it requires DDoS infrastructure providers to acquire compute resources behind providers that permit IP spoofing. IP spoofing itself has a long history on the internet, with a request for comment/best current practice (RFC/BCP) first written back in 2000 recommending that providers prevent this from occurring. However, adoption of this practice is still spotty on the internet.
At NANOG76, there was a proposal that these sorts of spoofed attacks could be traced by network operators in the path of the pre-amplification/reflection traffic (before it bounced off the reflectors). I personally started getting involved in this effort about two years ago. AWS operates a large global network and has network telemetry data that would help me identify pre-amplification/reflection traffic entering our network. This would allow me to triangulate the source network generating this. I then started engaging various networks directly that we connect to and provided them timestamps, spoofed source IP addresses, and specific protocols and ports involved with the traffic, hoping they could use their network telemetry to identify the customer generating it. From there, they’d engage with their customer to get the source shutdown or, failing that, implement packet filters on their customer to prevent spoofing.
Initially, only a few networks were capable of doing this well. This meant I had to spend a fair amount of energy in educating various networks around the globe on what spoofed traffic is, how to use their network telemetry to find it, and how to handle it. This was the most complicated and challenging part because this wasn’t on the radar of many networks out there. Up to this time, frontline network operations and abuse teams at various networks, including some very large ones, were not proficient in dealing with this.
The education I did included a variety of engagements, including sharing drawings with the day-in-the-life of a spoofed packet in a reflection attack, providing instructions on how to use their network telemetry tools, connecting them with their network telemetry vendors to help them, and even going so far as using other more exotic methods to identify which of their customers were spoofing and pointing out who they needed to analyze more deeply. In the end, it’s about getting other networks to be responsive and take action and, in the best cases, find spoofing on their own and act upon it.
Incredible! How did it feel accepting the award at the M3AAWG General Meeting in Brooklyn?
It was an honor to accept it and see some acknowledgement for the behind-the-scenes work that goes on to make the internet a better place.
What’s next for you in your work to suppress IP spoofing?
Continue tracing exercises and engaging with external providers. In particular, some of the network providers that experience challenges in dealing with spoofing and how we can improve their operations. Also, determining more effective ways to educate the hosting providers where IP spoofing is a common issue and making them implement proper default controls to not allow this behavior. Another aspect is being a force multiplier to enable others to spread the word and be part of the education process.
Looking ahead, what are some of your other goals for improving users’ online experiences and security?
Continually focusing on improving our DDoS defense strategies and working with customers to build tailored solutions that address some of their unique requirements. Across AWS, we have many services that are architected in different ways, so a key part of this is how do we raise the bar from a DDoS defense perspective across each of them. AWS customers also have their own unique architecture and protocols that can require developing new solutions to address their specific needs. On the disruption front, we will continue to focus on disrupting DDoS-as-a-service provider infrastructure beyond disrupting spoofing to disrupting botnets and the infrastructure associated with HTTP request floods.
With HTTP request floods being much more popular than byte-heavy and packet-heavy threat methods, it’s important to highlight the risks open proxies on the internet pose. Some of this emphasizes why there need to be some defaults in software packages to prevent misuse, in addition to network operators proactively identifying open proxies and taking appropriate action. Hosting providers should also recognize when their customer resources are communicating with large fleets of proxies and consider taking appropriate mitigations.
What are the most critical skills you would advise people need to be successful in network security?
I’m a huge proponent of being hands-on and diving into problems to truly understand how things are operating. Putting yourself outside your comfort zone, diving deep into the data to understand something, and translating that into outcomes and actions is something I highly encourage. After you immerse yourself in a particular domain, you can be much more effective at developing strategies and rapid prototyping to move forward. You can make incremental progress with small actions. You don’t have to wait for the perfect and complete solution to make some progress. I also encourage collaboration with others because there is incredible value in seeking out diverse opinions. There are resources out there to engage with, provided you’re willing to put in the work to learn and determine how you want to give back. The best people I’ve worked with don’t do it for public attention, blog posts, or social media status. They work in the background and don’t expect anything in return. They do it because of their desire to protect their customers and, where possible, the internet at large.
Lastly, if you had to pick an industry outside of security for your career, what would you be doing?
I’m over the maximum age allowed to start as an air traffic controller, so I suppose an air transport pilot or a locomotive engineer would be pretty neat.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
Health Information Trust Alliance (HITRUST) offers healthcare organizations a comprehensive and standardized approach to information security, privacy, and compliance. HITRUST Common Security Framework (HITRUST CSF) can be used by organizations to establish a robust security program, ensure patient data privacy, and assist with compliance with industry regulations. HITRUST CSF enhances security, streamlines compliance efforts, reduces risk, and contributes to overall security resiliency and the trustworthiness of healthcare entities in an increasingly challenging cybersecurity landscape.
While HITRUST primarily focuses on the healthcare industry, its framework and certification program are adaptable and applicable to other industries. The HITRUST CSF is a set of controls and requirements that organizations must comply with to achieve HITRUST certification. The HITRUST R2 assessment is the process by which organizations are evaluated against the requirements of the HITRUST CSF. During the assessment, an independent third party assessor examines the organization’s technical security controls, operational policies and procedures, and the implementation of all controls to determine if they meet the specified HITRUST requirements.
HITRUST r2 validated assessment certification is a comprehensive process that involves meeting numerous assessment requirements. The number of requirements can vary significantly, ranging from 500 to 2,000 depending on your environment’s risk factors and regulatory requirements. Attempting to address all of these requirements simultaneously especially when migrating systems to Amazon Web Services (AWS) can be overwhelming. By using a strategy of separating your compliance journey into environments and applications, you can streamline the process and achieve HITRUST compliance more efficiently and within a realistic timeframe.
In this blog post, we start by exploring the HITRUST domain structure, highlighting the security objective of each domain. We then show how you can use AWS configurable services to help meet these objectives.
Lastly, we present a simple and practical reference architecture with an AWS multi-account implementation that you can use as the foundation for hosting your AWS application, highlighting the phased approach for HITRUST compliance. Please note that this blog is intended to assist with using AWS services in a manner that supports an organization’s HITRUST compliance, but a HITRUST assessment is at an organizational level and involves controls that extend beyond the organization’s use of AWS.
HITRUST certification journey – Scope applications systems on AWS infrastructure:
The HITRUST controls needed for certification are structured within 19 HITRUST domains, covering a wide range of technical and administrative control requirements. To efficiently manage the scope of your certification assessment, start by focusing on the AWS landing zone, which serves as a critical foundational infrastructure component for running applications. When establishing the AWS landing zone, verify that it aligns with the AWS HITRUST security control requirements that are dependent on the scope of your assessment. Note that these 19 domains are a combination of technical controls and foundational administrative controls.
After you’ve set up a HITRUST compliant landing zone, you can begin evaluating your applications for HITRUST compliance as you migrate them to AWS. When you expand and migrate applications to the HITRUST-certified AWS landing zone assessed by your third party assessor, you can inherit the HITRUST controls required for application assessment directly from the landing zone. This simplifies and narrows the scope of your assessment activities.
Figure 1 that follows shows the two key phases and how a bottom-up phased approach can be structured with related HITRUST controls.
Figure 1: HITRUST Phase 1 and Phase 2 high-level components
The diagram illustrates:
An AWS landing zone environment as Phase 1 and its related HITRUST domain controls
An application system as Phase 2 and its related application system specific controls
HITRUST domain security objectives:
The HITRUST CSF based certification consists of 19 domains, which are broad categories that encompass various aspects of information security and privacy controls. These domains serve as a framework for your organization to assess and enhance its security posture. These domains cover a wide range of controls and practices related to information security, privacy, risk management, and compliance. Each domain consists of a set of control objectives and requirements that your organization must meet to achieve HITRUST certification.
The following table lists each domain, the key security objectives expected, and the AWS configurable services relevant to the security objectives. These are listed as a reference to give you an idea of the scope of each domain; the actual services and tools to meet specific HITRUST requirements will vary depending upon your scope and its HITRUST requirements.
Note: The information in this post is a general guideline and recommendation based on a phased approach for HITRUST r2 validated assessment. The examples are based on the information available at the time of publication and are not a full solution.
HITRUST domains, security objectives, and related AWS services
HITRUST domain
Summary of key security objectives expected in HITRUST domains
Related AWS configurable services
1. Information Protection Program
Implement information security management program.
Verify role suitability for employees, contractors, and third-party users.
Provide management guidance aligned with business goals and regulations.
Safeguard an organization’s information and assets.
Enhance awareness of information security among stakeholders.
Ensure the protection of information assets, prevent unauthorized disclosure, alteration, deletion, or harm, and maintain uninterrupted business operations.
Implement effective and repeatable technical vulnerability management to mitigate risks from exploited vulnerabilities.
Establish ownership and defined responsibilities for the protection of information assets within management.
Design controls in applications, including user-developed ones, to prevent errors, loss, unauthorized modification, or misuse of information. These controls should encompass input data validation, internal processing, and output data.
Maintain, protect, and make organizational information available.
Develop strategies and plans to prevent disruptions to business activities, safeguard critical processes from system failures or disasters, and ensure their prompt recovery.
Note: You can use AWS HITRUST-certified services to support your HITRUST compliance requirements. Use of these services in their default state doesn’t automatically ensure HITRUST certifiability. You must demonstrate compliance through formal formulation of policies, procedures, and implementation tailored to your scope, which involves configuring and customizing AWS HITRUST certified services to align precisely with HITRUST requirements within your scope and involves implementation of controls outside of the scope of the use of AWS services (such as appropriate organization-wide policies and procedures).
HITRUST phased approach – Reference architecture:
Figure 2 shows the recommended HITRUST Phase 1 and Phase 2 accounts and components within a landing zone.
Figure 2: HITRUST Phases 1 and 2 architecture including accounts and components
The reference architecture shown in Figure 2 illustrates:
A high-level structure of AWS accounts arranged in HITRUST Phase 1 and Phase 2
The accounts in HITRUST Phase 1 include:
Management account: The management account in the AWS landing zone is the primary account responsible for governing and managing the entire AWS environment.
Security account: The security account is dedicated to security and compliance functions, providing a centralized location for security-related tools and monitoring.
Central logging account: This account is designed for centralized logging and storage of logs from all other accounts, aiding in security analysis and troubleshooting.
Central audit: The central audit account is used for compliance monitoring, logging audit events, and verifying adherence to security standards.
DevOps account: DevOps accounts are used for software development and deployment, enabling continuous integration and delivery (CI/CD) processes.
Networking account: Networking accounts focus on network management, configuration, and monitoring to support reliable connectivity within the AWS environment.
DevSecOps account: DevSecOps accounts combine development, security, and operations to embed security practices throughout the software development lifecycle.
Shared services account: Shared services accounts host common resources, such as IAM services, that are shared across other accounts for centralized management.
The account group for HITRUST Phase 2 includes:
Tenant A – sample application workloads
Tenant B – sample application workloads
HITRUST Phase 1 – HITRUST foundational landing zone assessment phase:
In this phase you define the scope of assessment, including the specific AWS landing zone components and configurations that must be HITRUST compliant. The primary focus here is to evaluate the foundational infrastructure’s compliance with HITRUST controls. This involves a comprehensive review of policies and procedures, and implementation of all requirements within the landing zone scope. Assessing this phase separately enables you to verify that your foundational infrastructure adheres to HITRUST controls. Some of the policies, procedures, and configurations that are HITRUST assessed in this phase can be inherited across multiple applications’ assessments in later phases. Assessing this infrastructure once and then inheriting these controls for applications can be more efficient than assessing each application individually.
By establishing a secure and compliant foundation at the start, you can plan application assessments in later phases, making it simpler for subsequent applications to adhere to HITRUST requirements. This can streamline the compliance process and reduce the overall time and effort required. By assessing the landing zone separately, you can identify and address compliance gaps or issues in your foundational infrastructure, reducing the risk of non-compliance for the applications built upon it. Use the following high-level technical approach for this phase of assessment.
Build your AWS landing zone with HITRUST controls. See Building a landing zone for more information.
Use AWS and configure services according to the HITRUST requirements that are applicable to your infrastructure scope.
The HITRUST on AWS Quick Start guide is a reference for building HITRUST with one account. You can use the guide as a starting point to build a multi account architecture.
During this phase, you examine your AWS workload application accounts to conduct HITRUST assessments for application systems that are running within the AWS landing zone. You have the option to inherit environment-related controls that have been certified as HITRUST compliant within the landing zone in the previous phase.
The following key steps are recommended in this phase:
Readiness assessment for application scope: Conduct a thorough readiness assessment focused on the application scope, and define boundaries with scoped applications (AWS workload accounts).
HITRUST application controls: Gather specific HITRUST requirements for application scope by creating a HITRUST object for the application scope.
Scoped requirements analysis: Analyze requirements and use requirements that can be inherited from Phase 1 of the infrastructure assessment.
Gap analysis: Work with subject matter experts to conduct a gap analysis, and develop policies, procedures, and implementations for application specific controls.
Remediation: Remediate the gaps identified during the gap analysis activity.
Formal r2 assessment: Work with a third-party assessor to initiate a formal r2 validated assessment with HITRUST.
Conclusion
By breaking the compliance process into distinct phases, you can concentrate your resources on specific areas and prioritize essential assets accordingly. This approach supports a focused strategy, systematically addressing critical controls, and helping you to fulfill compliance requirements in a scalable manner. Obtaining the initial certification for the infrastructure and platform layers establishes a robust foundational architecture for subsequent phases, which involve application systems.
Earning certification at each phase provides tangible evidence of progress in your compliance journey. This achievement instills confidence in both internal and external stakeholders, affirming your organization’s commitment to security and compliance.
For guidance on achieving, maintaining, and automating compliance in the cloud, reach out to AWS Security Assurance Services (AWS SAS) or your account team. AWS SAS is a PCI QSAC and HITRUST External Assessor that can help by tying together applicable audit standards to AWS service-specific features and functionality. They can help you build on frameworks such as PCI DSS, HITRUST CSF, NIST, SOC 2, HIPAA, ISO 27001, GDPR, and CCPA.
Unstructured data is information that doesn’t conform to a predefined schema or isn’t organized according to a preset data model. Unstructured information may have a little or a lot of structure but in ways that are unexpected or inconsistent. Text, images, audio, and videos are common examples of unstructured data. Most companies produce and consume unstructured data such as documents, emails, web pages, engagement center phone calls, and social media. By some estimates, unstructured data can make up to 80–90% of all new enterprise data and is growing many times faster than structured data. After decades of digitizing everything in your enterprise, you may have an enormous amount of data, but with dormant value. However, with the help of AI and machine learning (ML), new software tools are now available to unearth the value of unstructured data.
In this post, we discuss how AWS can help you successfully address the challenges of extracting insights from unstructured data. We discuss various design patterns and architectures for extracting and cataloging valuable insights from unstructured data using AWS. Additionally, we show how to use AWS AI/ML services for analyzing unstructured data.
Why it’s challenging to process and manage unstructured data
Unstructured data makes up a large proportion of the data in the enterprise that can’t be stored in a traditional relational database management systems (RDBMS). Understanding the data, categorizing it, storing it, and extracting insights from it can be challenging. In addition, identifying incremental changes requires specialized patterns and detecting sensitive data and meeting compliance requirements calls for sophisticated functions. It can be difficult to integrate unstructured data with structured data from existing information systems. Some view structured and unstructured data as apples and oranges, instead of being complementary. But most important of all, the assumed dormant value in the unstructured data is a question mark, which can only be answered after these sophisticated techniques have been applied. Therefore, there is a need to being able to analyze and extract value from the data economically and flexibly.
Solution overview
Data and metadata discovery is one of the primary requirements in data analytics, where data consumers explore what data is available and in what format, and then consume or query it for analysis. If you can apply a schema on top of the dataset, then it’s straightforward to query because you can load the data into a database or impose a virtual table schema for querying. But in the case of unstructured data, metadata discovery is challenging because the raw data isn’t easily readable.
You can integrate different technologies or tools to build a solution. In this post, we explain how to integrate different AWS services to provide an end-to-end solution that includes data extraction, management, and governance.
The solution integrates data in three tiers. The first is the raw input data that gets ingested by source systems, the second is the output data that gets extracted from input data using AI, and the third is the metadata layer that maintains a relationship between them for data discovery.
The following is a high-level architecture of the solution we can build to process the unstructured data, assuming the input data is being ingested to the raw input object store.
The steps of the workflow are as follows:
Integrated AI services extract data from the unstructured data.
These services write the output to a data lake.
A metadata layer helps build the relationship between the raw data and AI extracted output. When the data and metadata are available for end-users, we can break the user access pattern into additional steps.
In the metadata catalog discovery step, we can use query engines to access the metadata for discovery and apply filters as per our analytics needs. Then we move to the next stage of accessing the actual data extracted from the raw unstructured data.
The end-user accesses the output of the AI services and uses the query engines to query the structured data available in the data lake. We can optionally integrate additional tools that help control access and provide governance.
There might be scenarios where, after accessing the AI extracted output, the end-user wants to access the original raw object (such as media files) for further analysis. Additionally, we need to make sure we have access control policies so the end-user has access only to the respective raw data they want to access.
Now that we understand the high-level architecture, let’s discuss what AWS services we can integrate in each step of the architecture to provide an end-to-end solution.
The following diagram is the enhanced version of our solution architecture, where we have integrated AWS services.
Let’s understand how these AWS services are integrated in detail. We have divided the steps into two broad user flows: data processing and metadata enrichment (Steps 1–3) and end-users accessing the data and metadata with fine-grained access control (Steps 4–6).
Various AI services (which we discuss in the next section) extract data from the unstructured datasets.
The output is written to an Amazon Simple Storage Service (Amazon S3) bucket (labeled Extracted JSON in the preceding diagram). Optionally, we can restructure the input raw objects for better partitioning, which can help while implementing fine-grained access control on the raw input data (labeled as the Partitioned bucket in the diagram).
After the initial data extraction phase, we can apply additional transformations to enrich the datasets using AWS Glue. We also build an additional metadata layer, which maintains a relationship between the raw S3 object path, the AI extracted output path, the optional enriched version S3 path, and any other metadata that will help the end-user discover the data.
The AI extracted output is expected to be available as a delimited file or in JSON format. We can create an AWS Glue Data Catalog table for querying using Athena or Redshift Spectrum. Like the previous step, we can use Lake Formation policies for fine-grained access control.
Lastly, the end-user accesses the raw unstructured data available in Amazon S3 for further analysis. We have proposed integrating Amazon S3 Access Points for access control at this layer. We explain this in detail later in this post.
Now let’s expand the following parts of the architecture to understand the implementation better:
Using AWS AI services to process unstructured data
Using S3 Access Points to integrate access control on raw S3 unstructured data
Process unstructured data with AWS AI services
As we discussed earlier, unstructured data can come in a variety of formats, such as text, audio, video, and images, and each type of data requires a different approach for extracting metadata. AWS AI services are designed to extract metadata from different types of unstructured data. The following are the most commonly used services for unstructured data processing:
Amazon Comprehend – This natural language processing (NLP) service uses ML to extract metadata from text data. It can analyze text in multiple languages, detect entities, extract key phrases, determine sentiment, and more. With Amazon Comprehend, you can easily gain insights from large volumes of text data such as extracting product entity, customer name, and sentiment from social media posts.
Amazon Transcribe – This speech-to-text service uses ML to convert speech to text and extract metadata from audio data. It can recognize multiple speakers, transcribe conversations, identify keywords, and more. With Amazon Transcribe, you can convert unstructured data such as customer support recordings into text and further derive insights from it.
Amazon Rekognition – This image and video analysis service uses ML to extract metadata from visual data. It can recognize objects, people, faces, and text, detect inappropriate content, and more. With Amazon Rekognition, you can easily analyze images and videos to gain insights such as identifying entity type (human or other) and identifying if the person is a known celebrity in an image.
Amazon Textract – You can use this ML service to extract metadata from scanned documents and images. It can extract text, tables, and forms from images, PDFs, and scanned documents. With Amazon Textract, you can digitize documents and extract data such as customer name, product name, product price, and date from an invoice.
Amazon SageMaker – This service enables you to build and deploy custom ML models for a wide range of use cases, including extracting metadata from unstructured data. With SageMaker, you can build custom models that are tailored to your specific needs, which can be particularly useful for extracting metadata from unstructured data that requires a high degree of accuracy or domain-specific knowledge.
Amazon Bedrock – This fully managed service offers a choice of high-performing foundation models (FMs) from leading AI companies like AI21 Labs, Anthropic, Cohere, Meta, Stability AI, and Amazon with a single API. It also offers a broad set of capabilities to build generative AI applications, simplifying development while maintaining privacy and security.
With these specialized AI services, you can efficiently extract metadata from unstructured data and use it for further analysis and insights. It’s important to note that each service has its own strengths and limitations, and choosing the right service for your specific use case is critical for achieving accurate and reliable results.
AWS AI services are available via various APIs, which enables you to integrate AI capabilities into your applications and workflows. AWS Step Functions is a serverless workflow service that allows you to coordinate and orchestrate multiple AWS services, including AI services, into a single workflow. This can be particularly useful when you need to process large amounts of unstructured data and perform multiple AI-related tasks, such as text analysis, image recognition, and NLP.
With Step Functions and AWS Lambda functions, you can create sophisticated workflows that include AI services and other AWS services. For instance, you can use Amazon S3 to store input data, invoke a Lambda function to trigger an Amazon Transcribe job to transcribe an audio file, and use the output to trigger an Amazon Comprehend analysis job to generate sentiment metadata for the transcribed text. This enables you to create complex, multi-step workflows that are straightforward to manage, scalable, and cost-effective.
The following is an example architecture that shows how Step Functions can help invoke AWS AI services using Lambda functions.
The workflow steps are as follows:
Unstructured data, such as text files, audio files, and video files, are ingested into the S3 raw bucket.
A Lambda function is triggered to read the data from the S3 bucket and call Step Functions to orchestrate the workflow required to extract the metadata.
The Step Functions workflow checks the type of file, calls the corresponding AWS AI service APIs, checks the job status, and performs any postprocessing required on the output.
AWS AI services can be accessed via APIs and invoked as batch jobs. To extract metadata from different types of unstructured data, you can use multiple AI services in sequence, with each service processing the corresponding file type.
After the Step Functions workflow completes the metadata extraction process and performs any required postprocessing, the resulting output is stored in an S3 bucket for cataloging.
Next, let’s understand how can we implement security or access control on both the extracted output as well as the raw input objects.
Implement access control on raw and processed data in Amazon S3
We just consider access controls for three types of data when managing unstructured data: the AI-extracted semi-structured output, the metadata, and the raw unstructured original files. When it comes to AI extracted output, it’s in JSON format and can be restricted via Lake Formation and Amazon DataZone. We recommend keeping the metadata (information that captures which unstructured datasets are already processed by the pipeline and available for analysis) open to your organization, which will enable metadata discovery across the organization.
To control access of raw unstructured data, you can integrate S3 Access Points and explore additional support in the future as AWS services evolve. S3 Access Points simplify data access for any AWS service or customer application that stores data in Amazon S3. Access points are named network endpoints that are attached to buckets that you can use to perform S3 object operations. Each access point has distinct permissions and network controls that Amazon S3 applies for any request that is made through that access point. Each access point enforces a customized access point policy that works in conjunction with the bucket policy that is attached to the underlying bucket. With S3 Access Points, you can create unique access control policies for each access point to easily control access to specific datasets within an S3 bucket. This works well in multi-tenant or shared bucket scenarios where users or teams are assigned to unique prefixes within one S3 bucket.
An access point can support a single user or application, or groups of users or applications within and across accounts, allowing separate management of each access point. Every access point is associated with a single bucket and contains a network origin control and a Block Public Access control. For example, you can create an access point with a network origin control that only permits storage access from your virtual private cloud (VPC), a logically isolated section of the AWS Cloud. You can also create an access point with the access point policy configured to only allow access to objects with a defined prefix or to objects with specific tags. You can also configure custom Block Public Access settings for each access point.
The following architecture provides an overview of how an end-user can get access to specific S3 objects by assuming a specific AWS Identity and Access Management (IAM) role. If you have a large number of S3 objects to control access, consider grouping the S3 objects, assigning them tags, and then defining access control by tags.
This post explained how you can use AWS AI services to extract readable data from unstructured datasets, build a metadata layer on top of them to allow data discovery, and build an access control mechanism on top of the raw S3 objects and extracted data using Lake Formation, Amazon DataZone, and S3 Access Points.
In addition to AWS AI services, you can also integrate large language models with vector databases to enable semantic or similarity search on top of unstructured datasets. To learn more about how to enable semantic search on unstructured data by integrating Amazon OpenSearch Service as a vector database, refer to Try semantic search with the Amazon OpenSearch Service vector engine.
As of writing this post, S3 Access Points is one of the best solutions to implement access control on raw S3 objects using tagging, but as AWS service features evolve in the future, you can explore alternative options as well.
About the Authors
Sakti Mishra is a Principal Solutions Architect at AWS, where he helps customers modernize their data architecture and define their end-to-end data strategy, including data security, accessibility, governance, and more. He is also the author of the book Simplify Big Data Analytics with Amazon EMR. Outside of work, Sakti enjoys learning new technologies, watching movies, and visiting places with family.
Bhavana Chirumamilla is a Senior Resident Architect at AWS with a strong passion for data and machine learning operations. She brings a wealth of experience and enthusiasm to help enterprises build effective data and ML strategies. In her spare time, Bhavana enjoys spending time with her family and engaging in various activities such as traveling, hiking, gardening, and watching documentaries.
Sheela Sonone is a Senior Resident Architect at AWS. She helps AWS customers make informed choices and trade-offs about accelerating their data, analytics, and AI/ML workloads and implementations. In her spare time, she enjoys spending time with her family—usually on tennis courts.
Daniel Bruno is a Principal Resident Architect at AWS. He had been building analytics and machine learning solutions for over 20 years and splits his time helping customers build data science programs and designing impactful ML products.
From day one, Amazon Web Services (AWS) has always believed it is essential that customers have control over their data, and choices for how they secure and manage that data in the cloud. Last year, we introduced the AWS Digital Sovereignty Pledge, our commitment to offering AWS customers the most advanced set of sovereignty controls and features available in the cloud. We pledged to work to understand the evolving needs and requirements of both customers and regulators, and to rapidly adapt and innovate to meet them. We committed to expanding our capabilities to allow customers to meet their digital sovereignty needs, without compromising on the performance, innovation, security, or scale of the AWS Cloud.
AWS offers the largest and most comprehensive cloud infrastructure globally. Our approach from the beginning has been to make AWS sovereign-by-design. We built data protection features and controls in the AWS Cloud with input from financial services, healthcare, and government customers—who are among the most security- and data privacy-conscious organizations in the world. This has led to innovations like the AWS Nitro System, which powers all our modern Amazon Elastic Compute Cloud (Amazon EC2) instances and provides a strong physical and logical security boundary to enforce access restrictions so that nobody, including AWS employees, can access customer data running in Amazon EC2. The security design of the Nitro System has also been independently validated by the NCC Group in a public report.
With AWS, customers have always had control over the location of their data. In Europe, customers that need to comply with European data residency requirements have the choice to deploy their data to any of our eight existing AWS Regions (Ireland, Frankfurt, London, Paris, Stockholm, Milan, Zurich, and Spain) to keep their data securely in Europe. To run their sensitive workloads, European customers can leverage the broadest and deepest portfolio of services, including AI, analytics, compute, database, Internet of Things (IoT), machine learning, mobile services, and storage. To further support customers, we’ve innovated to offer more control and choice over their data. For example, we announced further transparency and assurances, and new dedicated infrastructure options with AWS Dedicated Local Zones.
Announcing the AWS European Sovereign Cloud
When we speak to public sector and regulated industry customers in Europe, they share how they are facing incredible complexity and changing dynamics with an evolving sovereignty landscape. Customers tell us they want to adopt the cloud, but are facing increasing regulatory scrutiny over data location, European operational autonomy, and resilience. We’ve learned that these customers are concerned that they will have to choose between the full power of AWS or feature-limited sovereign cloud solutions. We’ve had deep engagements with European regulators, national cybersecurity authorities, and customers to understand how the sovereignty needs of customers can vary based on multiple factors, like location, sensitivity of workloads, and industry. These factors can impact their workload requirements, such as where their data can reside, who can access it, and the controls needed. AWS has a proven track record of innovation to address specialized workloads around the world.
Today, we’re excited to announce our plans to launch the AWS European Sovereign Cloud, a new, independent cloud for Europe, designed to help public sector organizations and customers in highly regulated industries meet their evolving sovereignty needs. We’re designing the AWS European Sovereign Cloud to be separate and independent from our existing Regions, with infrastructure located wholly within the European Union (EU), with the same security, availability, and performance our customers get from existing Regions today. To deliver enhanced operational resilience within the EU, only EU residents who are located in the EU will have control of the operations and support for the AWS European Sovereign Cloud. As with all current Regions, customers using the AWS European Sovereign Cloud will benefit from the full power of AWS with the same familiar architecture, expansive service portfolio, and APIs that millions of customers use today. The AWS European Sovereign Cloud will launch its first AWS Region in Germany available to all European customers.
The AWS European Sovereign Cloud will be sovereign-by-design, and will be built on more than a decade of experience operating multiple independent clouds for the most critical and restricted workloads. Like existing Regions, the AWS European Sovereign Cloud will be built for high availability and resiliency, and powered by the AWS Nitro System, to help ensure the confidentiality and integrity of customer data. Customers will have the control and assurance that AWS will not access or use customer data for any purpose without their agreement. AWS gives customers the strongest sovereignty controls among leading cloud providers. For customers with enhanced data residency needs, the AWS European Sovereign cloud is designed to go further and will allow customers to keep all metadata they create (such as the roles, permissions, resource labels, and configurations they use to run AWS) in the EU. The AWS European Sovereign Cloud will also be built with separate, in-Region billing and usage metering systems.
Delivering operational autonomy
The AWS European Sovereign Cloud will provide customers the capability to meet stringent operational autonomy and data residency requirements. To deliver enhanced data residency and operational resilience within the EU, the AWS European Sovereign Cloud infrastructure will be operated independently from existing AWS Regions. To assure independent operation of the AWS European Sovereign Cloud, only personnel who are EU residents, located in the EU, will have control of day-to-day operations, including access to data centers, technical support, and customer service.
We’re taking learnings from our deep engagements with European regulators and national cybersecurity authorities and applying them as we build the AWS European Sovereign Cloud, so that customers using the AWS European Sovereign Cloud can meet their data residency, operational autonomy, and resilience requirements. For example, we are looking forward to continuing to partner with Germany’s Federal Office for Information Security (BSI).
“The development of a European AWS Cloud will make it much easier for many public sector organizations and companies with high data security and data protection requirements to use AWS services. We are aware of the innovative power of modern cloud services and we want to help make them securely available for Germany and Europe. The C5 (Cloud Computing Compliance Criteria Catalogue), which was developed by the BSI, has significantly shaped cybersecurity cloud standards and AWS was in fact the first cloud service provider to receive the BSI’s C5 testate. In this respect, we are very pleased to constructively accompany the local development of an AWS Cloud, which will also contribute to European sovereignty, in terms of security.” — Claudia Plattner, President of the German Federal Office for Information Security (BSI)
Control without compromise
Though separate, the AWS European Sovereign Cloud will offer the same industry-leading architecture built for security and availability as other AWS Regions. This will include multiple Availability Zones (AZs), infrastructure that is placed in separate and distinct geographic locations, with enough distance to significantly reduce the risk of a single event impacting customers’ business continuity. Each AZ will have multiple layers of redundant power and networking to provide the highest level of resiliency. All AZs in the AWS European Sovereign Cloud will be interconnected with fully redundant, dedicated metro fiber, providing high-throughput, low-latency networking between AZs. All traffic between AZs will be encrypted. Customers who need more options to address stringent isolation and in-country data residency needs will be able to use Dedicated Local Zones or AWS Outposts to deploy AWS European Sovereign Cloud infrastructure in locations they select.
Continued AWS investment in Europe
The AWS European Sovereign Cloud represents continued AWS investment in Europe. AWS is committed to innovating to support European values and Europe’s digital future. We drive economic development through investing in infrastructure, jobs, and skills in communities and countries across Europe. We are creating thousands of high-quality jobs and investing billions of euros in European economies. Amazon has created more than 100,000 permanent jobs across the EU. Some of our largest AWS development teams are located in Europe, with key centers in Dublin, Dresden, and Berlin. As part of our continued commitment to contribute to the development of digital skills, we will hire and develop additional local personnel to operate and support the AWS European Sovereign Cloud.
Customers, partners, and regulators welcome the AWS European Sovereign Cloud
In the EU, hundreds of thousands of organizations of all sizes and across all industries are using AWS – from start-ups, to small and medium-sized businesses, to the largest enterprises, including telecommunication companies, public sector organizations, educational institutions, and government agencies. Organizations across Europe support the introduction of the AWS European Sovereign Cloud.
“As the market leader in enterprise application software with strong roots in Europe, SAP and AWS have long collaborated on behalf of customers to accelerate digital transformation around the world. The AWS European Sovereign Cloud provides further opportunities to strengthen our relationship in Europe by enabling us to expand the choices we offer to customers as they move to the cloud. We appreciate the ongoing partnership with AWS, and the new possibilities this investment can bring for our mutual customers across the region.” — Peter Pluim, President, SAP Enterprise Cloud Services and SAP Sovereign Cloud Services.
“The new AWS European Sovereign Cloud can be a game-changer for highly regulated business segments in the European Union. As a leading telecommunications provider in Germany, our digital transformation focuses on innovation, scalability, agility, and resilience to provide our customers with the best services and quality. This will now be paired with the highest levels of data protection and regulatory compliance that AWS delivers, and with a particular focus on digital sovereignty requirements. I am convinced that this new infrastructure offering has the potential to boost cloud adaptation of European companies and accelerate the digital transformation of regulated industries across the EU.” — Mallik Rao, Chief Technology and Information Officer, O2 Telefónica in Germany
“Deutsche Telekom welcomes the announcement of the AWS European Sovereign Cloud, which highlights AWS’s dedication to continuous innovation for European businesses. The AWS solution will provide greater choice for organizations when moving regulated workloads to the cloud and additional options to meet evolving digital governance requirements in the EU.” — Greg Hyttenrauch, senior vice president, Global Cloud Services at T-Systems
“Today, we stand at the cusp of a transformative era. The introduction of the AWS European Sovereign Cloud does not merely represent an infrastructural enhancement, it is a paradigm shift. This sophisticated framework will empower Dedalus to offer unparalleled services for storing patient data securely and efficiently in the AWS cloud. We remain committed, without compromise, to serving our European clientele with best-in-class solutions underpinned by trust and technological excellence.” — Andrea Fiumicelli, Chairman, Dedalus
“At de Volksbank, we believe in investing in a better Netherlands. To do this effectively, we need to have access to the latest technologies in order for us to continually be innovating and improving services for our customers. For this reason, we welcome the announcement of the European Sovereign Cloud which will allow European customers to easily demonstrate compliance with evolving regulations while still benefitting from the scale, security, and full suite of AWS services.” — Sebastiaan Kalshoven, Director IT/CTO, de Volksbank
“Eviden welcomes the launch of the AWS European Sovereign Cloud. This will help regulated industries and the public sector address the requirements of their sensitive workloads with a fully featured AWS cloud wholly operated in Europe. As an AWS Premier Tier Services Partner and leader in cybersecurity services in Europe, Eviden has an extensive track record in helping AWS customers formalize and mitigate their sovereignty risks. The AWS European Sovereign Cloud will allow Eviden to address a wider range of customers’ sovereignty needs.” — Yannick Tricaud, Head of Southern and Central Europe, Middle East, and Africa, Eviden, Atos Group
“We welcome the commitment of AWS to expand its infrastructure with an independent European cloud. This will give businesses and public sector organizations more choice in meeting digital sovereignty requirements. Cloud services are essential for the digitization of the public administration. With the “German Administration Cloud Strategy” and the “EVB-IT Cloud” contract standard, the foundations for cloud use in the public administration have been established. I am very pleased to work together with AWS to practically and collaboratively implement sovereignty in line with our cloud strategy.” — Dr. Markus Richter, CIO of the German federal government, Federal Ministry of the Interior
Our commitments to our customers
We remain committed to giving our customers control and choices to help meet their evolving digital sovereignty needs. We continue to innovate sovereignty features, controls, and assurances globally with AWS, without compromising on the full power of AWS.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
French
AWS Digital Sovereignty Pledge : Un nouveau cloud souverain, indépendant en Europe
Depuis sa création, Amazon Web Services (AWS) est convaincu qu’il est essentiel que les clients aient le contrôle de leurs données et puissent choisir la manière dont ils les sécurisent et les gèrent dans le cloud. L’année dernière, nous avons annoncé l’AWS Digital Sovereignty Pledge, notre engagement à offrir aux clients d’AWS l’ensemble le plus avancé de contrôles et de fonctionnalités de souveraineté disponibles dans le cloud. Nous nous sommes engagés à travailler pour comprendre les besoins et les exigences en constante évolution de nos clients et des régulateurs, et à nous adapter et innover rapidement pour y répondre. Nous nous sommes engagés à développer notre offre afin de permettre à nos clients de répondre à leurs besoins en matière de souveraineté numérique, sans compromis sur les performances, l’innovation, la sécurité ou encore l’étendue du Cloud AWS.
AWS propose l’infrastructure cloud la plus étendue et la plus complète au monde. Dès l’origine, notre approche a été de rendre AWS souverain dès la conception. Nous avons développé des fonctionnalités et des contrôles de protection des données dans le Cloud AWS en nous appuyant sur les retours de clients du secteur financier, de la santé et du secteur public, qui figurent parmi les organisations les plus soucieuses de la sécurité et de la confidentialité des données au monde. Cela a donné lieu à des innovations telles que AWS Nitro System, qui alimente toutes nos instances modernes Amazon Elastic Compute Cloud (Amazon EC2) et fournit une solide barrière de sécurité physique et logique pour implémenter les restrictions d’accès afin que personne, y compris les employés d’AWS, ne puisse accéder aux données des clients traitées dans Amazon EC2. La conception de la sécurité du Système Nitro a également été validée de manière indépendante par NCC Group dans un rapport public.
Avec AWS, les clients ont toujours eu le contrôle de l’emplacement de leurs données. En Europe, les clients qui doivent se conformer aux exigences européennes en matière de localisation des données peuvent choisir de déployer leurs données dans l’une de nos huit Régions AWS existantes (Irlande, Francfort, Londres, Paris, Stockholm, Milan, Zurich et Espagne) afin de conserver leurs données en toute sécurité en Europe. Pour exécuter leurs applications sensibles, les clients européens peuvent avoir recours à l’offre de services la plus étendue et la plus complète, de l’intelligence artificielle à l’analyse, du calcul aux bases de données, en passant par l’Internet des objets (IoT), l’apprentissage automatique, les services mobiles et le stockage. Pour soutenir davantage nos clients, nous avons innové pour offrir un plus grand choix en matière de contrôle sur leurs données. Par exemple, nous avons annoncé une transparence et des garanties de sécurité accrues, ainsi que de nouvelles options d’infrastructure dédiée appelées AWS Dedicated Local Zones.
Annonce de l’AWS European Sovereign Cloud Lorsque nous parlons à des clients du secteur public et des industries régulées en Europe, ils nous font part de l’incroyable complexité à laquelle ils sont confrontés dans un contexte de souveraineté en pleine évolution. Les clients nous disent qu’ils souhaitent adopter le cloud, mais qu’ils sont confrontés à des exigences réglementaires croissantes en matière de localisation des données, d’autonomie opérationnelle européenne et de résilience. Nous entendons que ces clients craignent de devoir choisir entre la pleine puissance d’AWS et des solutions de cloud souverain aux fonctionnalités limitées. Nous avons eu des contacts approfondis avec les régulateurs européens, les autorités nationales de cybersécurité et les clients afin de comprendre comment ces besoins de souveraineté peuvent varier en fonction de multiples facteurs tels que la localisation, la sensibilité des applications et le secteur d’activité. Ces facteurs peuvent avoir une incidence sur leurs exigences, comme l’endroit où leurs données peuvent être localisées, les personnes autorisées à y accéder et les contrôles nécessaires. AWS a fait ses preuves en matière d’innovation pour les applications spécialisées dans le monde entier.
Aujourd’hui, nous sommes heureux d’annoncer le lancement de l’AWS European Sovereign Cloud, un nouveau cloud indépendant pour l’Europe, conçu pour aider les organisations du secteur public et les clients des industries régulées à répondre à leurs besoins évolutifs en matière de souveraineté. Nous concevons l’AWS European Sovereign Cloud de manière à ce qu’il soit distinct et indépendant de nos Régions existantes, avec une infrastructure entièrement située dans l’Union européenne (UE), avec les mêmes niveaux de sécurité, de disponibilité et de performance que ceux dont bénéficient nos clients aujourd’hui dans les Régions existantes. Pour offrir une résilience opérationnelle accrue au sein de l’UE, seuls des résidents de l’UE qui se trouvent dans l’UE auront le contrôle sur l’exploitation et le support de l’AWS European Sovereign Cloud. Comme dans toutes les Régions existantes, les clients utilisant l’AWS European Sovereign Cloud bénéficieront de toute la puissance d’AWS avec la même architecture à laquelle ils sont habitués, le même portefeuille de services étendu et les mêmes API que ceux utilisés par des millions de clients aujourd’hui. L’AWS European Sovereign Cloud lancera sa première Région AWS en Allemagne, disponible pour tous les clients européens.
L’AWS European Sovereign Cloud sera souverain dès la conception et s’appuiera sur plus d’une décennie d’expérience dans l’exploitation de clouds indépendants pour les applications les plus critiques et les plus sensibles. À l’instar des Régions existantes, l’AWS European Sovereign Cloud sera conçu pour offrir une haute disponibilité et un haut niveau de résilience, et sera basé sur le Système AWS Nitro afin de garantir la confidentialité et l’intégrité des données des clients. Les clients auront le contrôle de leurs données et l’assurance qu’AWS n’y accèdera pas, ni ne les utilisera à aucune fin sans leur accord. AWS offre à ses clients les contrôles de souveraineté les plus puissants parmi les principaux fournisseurs de cloud. Pour les clients ayant des besoins accrus en matière de localisation des données, l’AWS European Sovereign Cloud est conçu pour aller plus loin et permettra aux clients de conserver toutes les métadonnées qu’ils créent (telles que les rôles de compte, les autorisations, les étiquettes de données et les configurations qu’ils utilisent au sein d’AWS) dans l’UE. L’AWS European Sovereign Cloud sera également doté de systèmes de facturation et de mesure de l’utilisation distincts et propres.
Apporter l’autonomie opérationnelle L’AWS European Sovereign Cloud permettra aux clients de répondre à des exigences strictes en matière d’autonomie opérationnelle et de localisation des données. Pour améliorer la localisation des données et la résilience opérationnelle au sein de l’UE, l’infrastructure de l’AWS European Sovereign Cloud sera exploitée indépendamment des Régions AWS existantes. Afin de garantir le fonctionnement indépendant de l’AWS European Sovereign Cloud, seul le personnel résidant de l’UE et situé dans l’UE contrôlera les opérations quotidiennes, y compris l’accès aux centres de données, l’assistance technique et le service client.
Nous tirons les enseignements de nos échanges approfondis auprès des régulateurs européens et des autorités nationales de cybersécurité et les appliquons à la création de l’AWS European Sovereign Cloud, afin que les clients qui l’utilisent puissent répondre à leurs exigences en matière de localisation des données, d’autonomie opérationnelle et de résilience. Par exemple, nous nous réjouissons de poursuivre notre partenariat avec l’Office fédéral allemand de la sécurité de l’information (BSI).
« Le développement d’un cloud AWS européen facilitera grandement l’utilisation des services AWS pour de nombreuses organisations du secteur public et des entreprises ayant des exigences élevées en matière de sécurité et de protection des données. Nous sommes conscients du pouvoir d’innovation des services cloud modernes et nous voulons contribuer à les rendre disponibles en toute sécurité pour l’Allemagne et l’Europe. Le C5 (Catalogue des critères de conformité du cloud computing), développé par le BSI, a considérablement façonné les normes de cybersécurité dans le cloud et AWS a été en fait le premier fournisseur de services cloud à recevoir la certification C5 du BSI. À cet égard, nous sommes très heureux d’accompagner de manière constructive le développement local d’un cloud AWS, qui contribuera également à la souveraineté européenne en termes de sécurité ». — Claudia Plattner, Présidente de l’Office fédéral allemand de la sécurité de l’information (BSI)
Contrôle sans compromis Bien que distinct, l’AWS European Sovereign Cloud proposera la même architecture à la pointe de l’industrie, conçue pour offrir la même sécurité et la même disponibilité que les autres Régions AWS. Cela inclura plusieurs Zones de Disponibilité (AZ), des infrastructures physiques placées dans des emplacements géographiques séparés et distincts, avec une distance suffisante pour réduire de manière significative le risque qu’un seul événement ait un impact sur la continuité des activités des clients. Chaque AZ disposera de plusieurs couches d’alimentation et de réseau redondantes pour fournir le plus haut niveau de résilience. Toutes les Zones de Disponibilité de l’AWS European Sovereign Cloud seront interconnectées par un réseau métropolitain de fibres dédié entièrement redondant, fournissant un réseau à haut débit et à faible latence entre les Zones de Disponibilité. Tous les échanges entre les AZ seront chiffrés. Les clients recherchant davantage d’options pour répondre à des besoins stricts en matière d’isolement et de localisation des données dans le pays pourront tirer parti des Dedicated Local Zones ou d’AWS Outposts pour déployer l’infrastructure de l’AWS European Sovereign Cloud sur les sites de leur choix.
Un investissement continu d’AWS en Europe L’AWS European Sovereign Cloud s’inscrit dans un investissement continu d’AWS en Europe. AWS s’engage à innover pour soutenir les valeurs européennes et l’avenir numérique de l’Europe.
Nous créons des milliers d’emplois qualifiés et investissons des milliards d’euros dans l’économie européenne. Amazon a créé plus de 100 000 emplois permanents dans l’UE.
Nous favorisons le développement économique en investissant dans les infrastructures, les emplois et les compétences dans les territoires et les pays d’Europe. Certaines des plus grandes équipes de développement d’AWS sont situées en Europe, avec des centres majeurs à Dublin, Dresde et Berlin. Dans le cadre de notre engagement continu à contribuer au développement des compétences numériques, nous recruterons et formerons du personnel local supplémentaire pour exploiter et soutenir l’AWS European Sovereign Cloud.
Les clients, partenaires et régulateurs accueillent favorablement l’AWS European Sovereign Cloud Dans l’UE, des centaines de milliers d’organisations de toutes tailles et de tous secteurs utilisent AWS, qu’il s’agisse de start-ups, de petites et moyennes entreprises ou de grandes entreprises, y compris des sociétés de télécommunications, des organisations du secteur public, des établissements d’enseignement ou des agences gouvernementales. Des organisations de toute l’Europe accueillent favorablement l’AWS European Sovereign Cloud.
« En tant que leader du marché des logiciels de gestion d’entreprise fortement ancré en Europe, SAP collabore depuis longtemps avec AWS pour le compte de ses clients, afin d’accélérer la transformation numérique dans le monde entier. L’AWS European Sovereign Cloud offre de nouvelles opportunités de renforcer notre relation en Europe en nous permettant d’élargir les choix que nous offrons aux clients lorsqu’ils passent au cloud. Nous apprécions le partenariat en cours avec AWS, et les nouvelles possibilités que cet investissement peut apporter à nos clients mutuels dans toute la région. » — Peter Pluim, Président, SAP Enterprise Cloud Services and SAP Sovereign Cloud Services.
« Le nouvel AWS European Sovereign Cloud peut changer la donne pour les secteurs d’activité très réglementés de l’Union européenne. En tant que fournisseur de télécommunications de premier plan en Allemagne, notre transformation numérique se concentre sur l’innovation, l’évolutivité, l’agilité et la résilience afin de fournir à nos clients les meilleurs services et la meilleure qualité. Cela sera désormais associé aux plus hauts niveaux de protection des données et de conformité réglementaire qu’offre AWS, avec un accent particulier sur les exigences de souveraineté numérique. Je suis convaincu que cette nouvelle offre d’infrastructure a le potentiel de stimuler l’adaptation au cloud des entreprises européennes et d’accélérer la transformation numérique des industries réglementées à travers l’UE. » — Mallik Rao, Chief Technology and Information Officer, O2 Telefónica, Allemagne
« Deutsche Telekom se réjouit de l’annonce de l’AWS European Sovereign Cloud, qui souligne la volonté d’AWS d’innover en permanence pour les entreprises européennes. La solution d’AWS offrira un plus grand choix aux organisations lorsqu’elles migreront des applications réglementées vers le cloud, ainsi que des options supplémentaires pour répondre à l’évolution des exigences en matière de gouvernance numérique dans l’UE. » — Greg Hyttenrauch, vice-président senior, Global Cloud Services chez T-Systems
« Aujourd’hui, nous sommes à l’aube d’une ère de transformation. Le lancement de l’AWS European Sovereign Cloud ne représente pas seulement une amélioration de l’infrastructure, c’est un changement de paradigme. Ce cadre sophistiqué permettra à Dedalus d’offrir des services inégalés pour le stockage sécurisé et efficace des données des patients dans le cloud AWS. Nous restons engagés, sans compromis, à servir notre clientèle européenne avec les meilleures solutions de leur catégorie, étayées par la confiance et l’excellence technologique ». — Andrea Fiumicelli, Chairman at Dedalus
« À de Volksbank, nous croyons qu’il faut investir dans l’avenir des Pays-Bas. Pour y parvenir efficacement, nous devons avoir accès aux technologies les plus récentes afin d’innover en permanence et d’améliorer les services offerts à nos clients. C’est pourquoi nous nous réjouissons de l’annonce de l’AWS European Sovereign Cloud, qui permettra aux clients européens de démontrer facilement leur conformité aux réglementations en constante évolution tout en bénéficiant de l’étendue, de la sécurité et de la suite complète de services AWS ». — Sebastiaan Kalshoven, Director IT/CTO, de Volksbank
« Eviden se réjouit du lancement de l’AWS European Sovereign Cloud. Celui-ci aidera les industries réglementées et le secteur public à satisfaire leurs exigences pour les applications les plus sensibles, grâce à un Cloud AWS doté de toutes ses fonctionnalités et entièrement opéré en Europe. En tant que partenaire AWS Premier Tier Services et leader des services de cybersécurité en Europe, Eviden a une longue expérience dans l’accompagnement de clients AWS pour formaliser et maîtriser leurs risques en termes de souveraineté. L’AWS European Sovereign Cloud permettra à Eviden de répondre à un plus grand nombre de besoins de ses clients en matière de souveraineté ». — Yannick Tricaud, Head of Southern and Central Europe, Middle East and Africa, Eviden, Atos Group
« Nous saluons l’engagement d’AWS d’étendre son infrastructure avec un cloud européen indépendant. Les entreprises et les organisations du secteur public auront ainsi plus de choix pour répondre aux exigences de souveraineté numérique. Les services cloud sont essentiels pour la numérisation de l’administration publique. La “stratégie de l’administration allemande en matière de cloud” et la norme contractuelle “EVB-IT Cloud” ont constitué les bases de l’utilisation du cloud dans l’administration publique. Je suis très heureux de travailler avec AWS pour mettre en œuvre de manière pratique et collaborative la souveraineté, conformément à notre stratégie cloud. » — Markus Richter, DSI du gouvernement fédéral allemand, ministère fédéral de l’Intérieur.
Nos engagements envers nos clients Nous restons déterminés à donner à nos clients le contrôle et les choix nécessaires pour répondre à l’évolution de leurs besoins en matière de souveraineté numérique. Nous continuons d’innover en matière de fonctionnalités, de contrôles et de garanties de souveraineté au niveau mondial au sein d’AWS, tout en fournissant sans compromis et sans restriction la pleine puissance d’AWS.
AWS Digital Sovereignty Pledge: Ankündigung der neuen, unabhängigen AWS European Sovereign Cloud
Amazon Web Services (AWS) war immer der Meinung, dass es wichtig ist, dass Kunden die volle Kontrolle über ihre Daten haben. Kunden sollen die Wahl haben, wie sie diese Daten in der Cloud absichern und verwalten.
Letztes Jahr haben wir unseren „AWS Digital Sovereignty Pledge“ vorgestellt: Unser Versprechen, allen AWS-Kunden ohne Kompromisse die fortschrittlichsten Steuerungsmöglichkeiten für Souveränitätsanforderungen und Funktionen in der Cloud anzubieten. Wir haben uns dazu verpflichtet, die sich wandelnden Anforderungen von Kunden und Aufsichtsbehörden zu verstehen und sie mit innovativen Angeboten zu adressieren. Wir bauen unser Angebot so aus, dass Kunden ihre Bedürfnisse an digitale Souveränität erfüllen können, ohne Kompromisse bei der Leistungsfähigkeit, Innovationskraft, Sicherheit und Skalierbarkeit der AWS-Cloud einzugehen.
AWS bietet die größte und umfassendste Cloud-Infrastruktur weltweit. Von Anfang an haben wir bei der AWS-Cloud einen „sovereign-by-design“-Ansatz verfolgt. Wir haben mit Hilfe von Kunden aus besonders regulierten Branchen, wie z.B. Finanzdienstleistungen, Gesundheit, Staat und Verwaltung, Funktionen und Steuerungsmöglichkeiten für Datenschutz und Datensicherheit entwickelt. Dieses Vorgehen hat zu Innovationen wie dem AWS Nitro System geführt, das heute die Grundlage für alle modernen Amazon Elastic Compute Cloud (Amazon EC2) Instanzen und Confidential Computing auf AWS bildet. AWS Nitro setzt auf eine starke physikalische und logische Sicherheitsabgrenzung und realisiert damit Zugriffsbeschränkungen, die unautorisierte Zugriffe auf Kundendaten in EC2 unmöglich machen – das gilt auch für AWS-Personal. Die NCC Group hat das Sicherheitsdesign von AWS Nitro im Rahmen einer unabhängigen Untersuchung in einem öffentlichen Bericht validiert.
Mit AWS hatten und haben Kunden stets die Kontrolle über den Speicherort ihrer Daten. Kunden, die spezifische europäische Vorgaben zum Ort der Datenverarbeitung einhalten müssen, haben die Wahl, ihre Daten in jeder unserer bestehenden acht AWS-Regionen (Frankfurt, Irland, London, Mailand, Paris, Stockholm, Spanien und Zürich) zu verarbeiten und sicher innerhalb Europas zu speichern. Europäische Kunden können ihre kritischen Workloads auf Basis des weltweit umfangreichsten und am weitesten verbreiteten Portfolios an Diensten betreiben – dazu zählen AI, Analytics, Compute, Datenbanken, Internet of Things (IoT), Machine Learning (ML), Mobile Services und Storage. Wir haben Innovationen in den Bereichen Datenverwaltung und Kontrolle realisiert, um unsere Kunden besser zu unterstützen. Zum Beispiel haben wir weitergehende Transparenz und zusätzliche Zusicherungen sowie neue Optionen für dedizierte Infrastruktur mit AWS Dedicated Local Zones angekündigt.
Ankündigung der AWS European Sovereign Cloud Kunden aus dem öffentlichen Sektor und aus regulierten Industrien in Europa berichten uns immer wieder, mit welcher Komplexität und Dynamik sie im Bereich Souveränität konfrontiert werden. Wir hören von unseren Kunden, dass sie die Cloud nutzen möchten, aber gleichzeitig zusätzliche Anforderungen im Zusammenhang mit dem Ort der Datenverarbeitung, der betrieblichen Autonomie und der operativen Souveränität erfüllen müssen.
Kunden befürchten, dass sie sich zwischen der vollen Leistung von AWS und souveränen Cloud-Lösungen mit eingeschränkter Funktion entscheiden müssen. Wir haben intensiv mit Aufsichts- und Cybersicherheitsbehörden sowie Kunden aus Deutschland und anderen europäischen Ländern zusammengearbeitet, um zu verstehen, wie Souveränitätsbedürfnisse aufgrund verschiedener Faktoren wie Standort, Klassifikation der Workloads und Branche variieren können. Diese Faktoren können sich auf Workload-Anforderungen auswirken, z. B. darauf, wo sich diese Daten befinden dürfen, wer darauf zugreifen kann und welche Steuerungsmöglichkeiten erforderlich sind. AWS hat eine nachgewiesene Erfolgsbilanz insbesondere für innovative Lösungen zur Verarbeitung spezialisierter Workloads auf der ganzen Welt.
Wir freuen uns, heute die AWS European Sovereign Cloud ankündigen zu können: Eine neue, unabhängige Cloud für Europa. Sie soll Kunden aus dem öffentlichen Sektor und stark regulierten Industrien (z.B. Betreiber kritischer Infrastrukturen („KRITIS“)) dabei helfen, spezifische gesetzliche Anforderungen an den Ort der Datenverarbeitung und den Betrieb der Cloud zu erfüllen. Die AWS European Sovereign Cloud wird sich in der Europäischen Union (EU) befinden und dort betrieben. Sie wird physisch und logisch von den bestehenden AWS-Regionen getrennt sein und dieselbe Sicherheit, Verfügbarkeit und Leistung wie die bestehenden AWS-Regionen bieten. Die Kontrolle über den Betrieb und den Support der AWS European Sovereign Cloud wird ausschließlich von AWS-Personal ausgeübt, das in der EU ansässig ist und sich in der EU aufhält.
Wie schon bei den bestehenden AWS-Regionen, werden Kunden, welche die AWS European Sovereign Cloud nutzen, von dem gesamten AWS-Leistungsumfang profitieren. Dazu zählen die gewohnte Architektur, das umfangreiche Service-Portfolio und die APIs, die heute schon von Millionen von Kunden verwendet werden. Die AWS European Sovereign Cloud wird mit ihrer ersten AWS-Region in Deutschland starten und allen Kunden in Europa zur Verfügung stehen.
Die AWS European Sovereign Cloud wird “sovereign-by-design” sein und basiert auf mehr als zehn Jahren Erfahrung beim Betrieb mehrerer unabhängiger Clouds für besonders kritische und vertrauliche Workloads. Wie schon bei unseren bestehenden AWS-Regionen wird die AWS European Sovereign Cloud für Hochverfügbarkeit und Ausfallsicherheit ausgelegt sein und auf dem AWS Nitro System aufbauen, um die Vertraulichkeit und Integrität von Kundendaten sicherzustellen. Kunden haben die Kontrolle und Gewissheit darüber, dass AWS nicht ohne ihr Einverständnis auf Kundendaten zugreift oder sie für andere Zwecke verwendet. Die AWS European Sovereign Cloud ist so gestaltet, dass nicht nur alle Kundendaten, sondern auch alle Metadaten, die durch Kunden angelegt werden (z.B. Rollen, Zugriffsrechte, Labels für Ressourcen und Konfigurationsinformationen), innerhalb der EU verbleiben. Die AWS European Sovereign Cloud verfügt über unabhängige Systeme für das Rechnungswesen und zur Nutzungsmessung.
„Die neue AWS European Sovereign Cloud kann ein Game Changer für stark regulierte Geschäftsbereiche in der Europäischen Union sein. Als führender Telekommunikationsanbieter in Deutschland konzentriert sich unsere digitale Transformation auf Innovation, Skalierbarkeit, Agilität und Resilienz, um unseren Kunden die besten Dienste und die beste Qualität zu bieten. Dies wird nun von AWS mit dem höchsten Datenschutzniveau unter Einhaltung der regulatorischen Anforderungen vereint mit einem besonderen Schwerpunkt auf die Anforderungen an digitale Souveränität. Ich bin überzeugt, dass dieses neue Infrastrukturangebot das Potenzial hat, die Cloud-Adaption von europäischen Unternehmen voranzutreiben und die digitale Transformation regulierter Branchen in der EU zu beschleunigen.“ — Mallik Rao, Chief Technology and Information Officer bei O2 Telefónica in Deutschland
Sicherstellung operativer Autonomie Die AWS European Sovereign Cloud bietet Kunden die Möglichkeit, strenge Anforderungen an Betriebsautonomie und den Ort der Datenverarbeitung zu erfüllen. Um eine Datenverarbeitung und operative Souveränität innerhalb der EU zu gewährleisten, wird die AWS European Sovereign Cloud-Infrastruktur unabhängig von bestehenden AWS-Regionen betrieben. Um den unabhängigen Betrieb der AWS European Sovereign Cloud zu gewährleisten, hat nur Personal, das in der EU ansässig ist und sich in der EU aufhält die Kontrolle über den täglichen Betrieb. Dazu zählen der Zugang zu Rechenzentren, der technische Support und der Kundenservice.
Wir nutzen die Erkenntnisse aus unserer intensiven Zusammenarbeit mit Aufsichts- und Cybersicherheitsbehörden in Europa beim Aufbau der AWS European Sovereign Cloud, damit Kunden ihren Anforderungen an die Kontrolle über den Speicher- und Verarbeitungsort ihrer Daten, der betrieblichen Autonomie und der operativen Souveränität gerecht werden können. Wir freuen uns, mit dem Bundesamt für Sicherheit in der Informationstechnik (BSI) auch bei der Umsetzung der AWS European Sovereign Cloud zu kooperieren:
„Der Aufbau einer europäischen AWS-Cloud wird es für viele Behörden und Unternehmen mit hohen Anforderungen an die Datensicherheit und den Datenschutz deutlich leichter machen, die AWS-Services zu nutzen. Wir wissen um die Innovationskraft moderner Cloud-Dienste und wir wollen mithelfen, sie für Deutschland und Europa sicher verfügbar zu machen. Das BSI hat mit dem Kriterienkatalog C5 die Cybersicherheit im Cloud Computing bereits maßgeblich beeinflusst, und tatsächlich war AWS der erste Cloud Service Provider, der das C5-Testat des BSI erhalten hat. Insofern freuen wir uns sehr, den hiesigen Aufbau einer AWS-Cloud, die auch einen Beitrag zur europäischen Souveränität leisten wird, im Hinblick auf die Sicherheit konstruktiv zu begleiten.“ — Claudia Plattner, Präsidentin, deutsches Bundesamt für Sicherheit in der Informationstechnik (BSI)
Kontrolle ohne Kompromisse Obwohl sie separat betrieben wird, bietet die AWS European Sovereign Cloud dieselbe branchenführende Architektur, die auf Sicherheit und Verfügbarkeit ausgelegt ist wie andere AWS-Regionen. Dazu gehören mehrere Verfügbarkeitszonen (Availability Zones, AZs) – eine Infrastruktur, die sich an verschiedenen voneinander getrennten geografischen Standorten befindet. Diese räumliche Trennung verringert signifikant das Risiko, dass ein Zwischenfall an einem einzelnen Standort den Geschäftsbetrieb des Kunden beeinträchtigt. Jede Verfügbarkeitszone besitzt eine autarke Stromversorgung und Kühlung und verfügt über redundante Netzwerkanbindungen, um ein Höchstmaß an Ausfallsicherheit zu gewährleisten. Zudem zeichnet sich jede Verfügbarkeitszone durch eine hohe physische Sicherheit aus. Alle AZs in der AWS European Sovereign Cloud werden über vollständig redundante, dedizierte Metro-Glasfaser miteinander verbunden und ermöglichen so eine Vernetzung mit hohem Durchsatz und niedriger Latenz zwischen den AZs. Der gesamte Datenverkehr zwischen AZs wird verschlüsselt. Für besonders strikte Anforderungen an die Trennung von Daten und den Ort der Datenverarbeitung innerhalb eines Landes bieten bestehende Angebote wie AWS Dedicated Local Zones oder AWS Outposts zusätzliche Optionen. Damit können Kunden die AWS European Sovereign Cloud Infrastruktur auf selbstgewählte Standorte erweitern.
Kontinuierliche AWS-Investitionen in Deutschland und Europa Mit der AWS European Sovereign Cloud setzt AWS seine Investitionen in Deutschland und Europa fort. AWS entwickelt Innovationen, um europäische Werte und die digitale Zukunft in Deutschland und Europa zu unterstützen. Wir treiben die wirtschaftliche Entwicklung voran, indem wir in Infrastruktur, Arbeitsplätze und Ausbildung in ganz Europa investieren. Wir schaffen Tausende von hochwertigen Arbeitsplätzen und investieren Milliarden von Euro in europäische Volkswirtschaften. Amazon hat mehr als 100.000 dauerhafte Arbeitsplätze innerhalb der EU geschaffen.
„Die deutsche und europäische Wirtschaft befindet sich auf Digitalisierungskurs. Insbesondere der starke deutsche Mittelstand braucht eine souveräne Digitalinfrastruktur, die höchsten Anforderungen genügt, um auch weiterhin wettbewerbsfähig im globalen Markt zu sein. Für unsere digitale Unabhängigkeit ist wichtig, dass Rechenleistungen vor Ort in Deutschland entstehen und in unseren Digitalstandort investiert wird. Wir begrüßen daher die Ankündigung von AWS, die Cloud für Europa in Deutschland anzusiedeln.“ — Stefan Schnorr, Staatssekretär im deutschen Bundesministerium für Digitales und Verkehr
Einige der größten Entwicklungsteams von AWS sind in Deutschland und Europa angesiedelt, mit Standorten in Aachen, Berlin, Dresden, Tübingen und Dublin. Da wir uns verpflichtet fühlen, einen langfristigen Beitrag zur Entwicklung digitaler Kompetenzen zu leisten, wird AWS zusätzliches Personal vor Ort für die AWS European Sovereign Cloud einstellen und ausbilden.
Kunden, Partner und Aufsichtsbehörden begrüßen die AWS European Sovereign Cloud In der EU nutzen Hunderttausende Organisationen aller Größen und Branchen AWS – von Start-ups über kleine und mittlere Unternehmen bis hin zu den größten Unternehmen, einschließlich Telekommunikationsunternehmen, Organisationen des öffentlichen Sektors, Bildungseinrichtungen und Regierungsbehörden. Europaweit unterstützen Organisationen die Einführung der AWS European Sovereign Cloud. Für Kunden wird die AWS European Sovereign Cloud neue Möglichkeiten im Cloudeinsatz eröffnen.
„Wir begrüßen das Engagement von AWS, seine Infrastruktur mit einer unabhängigen europäischen Cloud auszubauen. So erhalten Unternehmen und Organisationen der öffentlichen Hand mehr Auswahlmöglichkeiten bei der Erfüllung der Anforderungen an digitale Souveränität. Cloud-Services sind für die Digitalisierung der öffentlichen Verwaltung unerlässlich. Mit der Deutschen Verwaltungscloud-Strategie und dem Vertragsstandard EVB-IT Cloud wurden die Grundlagen für die Cloud-Nutzung in der Verwaltung geschaffen. Ich freue mich sehr, gemeinsam mit AWS Souveränität im Sinne unserer Cloud-Strategie praktisch und partnerschaftlich umzusetzen.” — Dr. Markus Richter, Staatssekretär im deutschen Bundesministerium des Innern und für Heimat sowie Beauftragter der Bundesregierung für Informationstechnik (CIO des Bundes)
„Als Marktführer für Geschäftssoftware mit starken Wurzeln in Europa, arbeitet SAP seit langem im Interesse der Kunden mit AWS zusammen, um die digitale Transformation auf der ganzen Welt zu beschleunigen. Die AWS European Sovereign Cloud bietet weitere Möglichkeiten, unsere Beziehung in Europa zu stärken, indem wir die Möglichkeiten, die wir unseren Kunden beim Wechsel in die Cloud bieten, erweitern können. Wir schätzen die fortlaufende Zusammenarbeit mit AWS und die neuen Möglichkeiten, die diese Investition für unsere gemeinsamen Kunden in der gesamten Region mit sich bringen kann.“ — Peter Pluim, President – SAP Enterprise Cloud Services und SAP Sovereign Cloud Services
„Heute stehen wir an der Schwelle zu einer transformativen Ära. Die Einführung der AWS European Sovereign Cloud stellt nicht nur eine infrastrukturelle Erweiterung dar, sondern ist ein Paradigmenwechsel. Dieses hochentwickelte Framework wird Dedalus in die Lage versetzen, unvergleichliche Dienste für die sichere und effiziente Speicherung von Patientendaten in der AWS-Cloud anzubieten. Wir bleiben kompromisslos dem Ziel verpflichtet, unseren europäischen Kunden erstklassige Lösungen zu bieten, die auf Vertrauen und technologischer Exzellenz basieren.“ — Andrea Fiumicelli, Chairman bei Dedalus
„Die Deutsche Telekom begrüßt die Ankündigung der AWS European Sovereign Cloud, die das Engagement von AWS für fortwährende Innovationen für europäische Unternehmen unterstreicht. Diese AWS-Lösung wird Unternehmen eine noch größere Auswahl bieten, wenn sie kritische Workloads in die AWS-Cloud verlagern, und zusätzliche Optionen zur Erfüllung der sich entwickelnden Anforderungen an die digitale Governance in der EU.” — Greg Hyttenrauch, Senior Vice President, Global Cloud Services bei T-Systems
„Wir begrüßen die AWS European Sovereign Cloud als neues Angebot innerhalb von AWS, um die komplexesten regulatorischen Anforderungen an die Datenresidenz und betrieblichen Erfordernisse in ganz Europa zu adressieren.“ — Bernhard Wagensommer, Vice President Prinect bei der Heidelberger Druckmaschinen AG
„Die AWS European Sovereign Cloud wird neue Branchenmaßstäbe setzen und sicherstellen, dass Finanzdienstleistungsunternehmen noch mehr Optionen innerhalb von AWS haben, um die wachsenden Anforderungen an die digitale Souveränität hinsichtlich der Datenresidenz und operativen Autonomie in der EU zu erfüllen.“ — Gerhard Koestler, Chief Information Officer bei Raisin
„Mit einem starken Fokus auf Datenschutz, Sicherheit und regulatorischer Compliance unterstreicht die AWS European Sovereign Cloud das Engagement von AWS, die höchsten Standards für die digitale Souveränität von Finanzdienstleistern zu fördern. Dieser zusätzliche robuste Rahmen ermöglicht es Unternehmen wie unserem, in einer sicheren Umgebung erfolgreich zu sein, in der Daten geschützt sind und die Einhaltung höchster Standards leichter denn je wird.“ — Andreas Schranzhofer, Chief Technology Officer bei Scalable Capital
„Die AWS European Sovereign Cloud ist ein wichtiges, zusätzliches Angebot von AWS, das hochregulierten Branchen, Organisationen der öffentlichen Hand und Regierungsbehörden in Deutschland weitere Optionen bietet, um strengste regulatorische Anforderungen an den Datenschutz in der Cloud noch einfacher umzusetzen. Als AWS Advanced Tier Services Partner, AWS Solution Provider und AWS Public Sector Partner beraten und unterstützen wir kritische Infrastrukturen (KRITIS) bei der erfolgreichen Implementierung. Das neue Angebot von AWS ist ein wichtiger Impuls für Innovationen und Digitalisierung in Deutschland.“ — Martin Wibbe, CEO bei Materna
„Als eines der größten deutschen IT-Unternehmen und strategischer AWS-Partner begrüßt msg ausdrücklich die Ankündigung der AWS European Sovereign Cloud. Für uns als Anbieter von Software as a Service (SaaS) und Consulting Advisor für Kunden mit spezifischen Datenschutzanforderungen ermöglicht die Schaffung einer eigenständigen europäischen Cloud, unseren Kunden dabei zu helfen, die Einhaltung sich entwickelnder Vorschriften leichter nachzuweisen. Diese spannende Ankündigung steht im Einklang mit unserer Cloud-Strategie. Wir betrachten dies als Chance, um unsere Partnerschaft mit AWS zu stärken und die Entwicklung der Cloud in Deutschland voranzutreiben.“ — Dr. Jürgen Zehetmaier, CEO von msg
Unsere Verpflichtung gegenüber unseren Kunden Um Kunden bei der Erfüllung der sich wandelnden Souveränitätsanforderungen zu unterstützen, entwickelt AWS fortlaufend innovative Features, Kontrollen und Zusicherungen, ohne die Leistungsfähigkeit der AWS Cloud zu beeinträchtigen.
AWS Digital Sovereignty Pledge: Annuncio di un nuovo cloud sovrano e indipendente in Europa
Fin dal primo giorno, abbiamo sempre creduto che fosse essenziale che tutti i clienti avessero il controllo sui propri dati e sulle scelte di come proteggerli e gestirli nel cloud. L’anno scorso abbiamo introdotto l’AWS Digital Sovereignty Pledge, il nostro impegno a offrire ai clienti AWS il set più avanzato di controlli e funzionalità di sovranità disponibili nel cloud. Ci siamo impegnati a lavorare per comprendere le esigenze e le necessità in costante evoluzione sia dei clienti che delle autorità di regolamentazione, e per adattarci e innovare rapidamente per soddisfarli. Ci siamo impegnati ad espandere le nostre funzionalità per consentire ai clienti di soddisfare le loro esigenze di sovranità digitale senza compromettere le prestazioni, l’innovazione, la sicurezza o la scalabilità del cloud AWS.
AWS offre l’infrastruttura cloud più grande e completa a livello globale. Il nostro approccio fin dall’inizio è stato quello di rendere il cloud AWS sovrano by design. Abbiamo creato funzionalità e controlli di protezione dei dati nel cloud AWS confrontandoci con i clienti che operano in settori quali i servizi finanziari e l’assistenza sanitaria, che sono in assoluto tra le organizzazioni più attente alla sicurezza e alla privacy dei dati. Ciò ha portato a innovazioni come AWS Nitro System, che alimenta tutte le nostre moderne istanze Amazon Elastic Compute Cloud (Amazon EC2) e fornisce un solido standard di sicurezza fisico e logico-infrastrutturale al fine di imporre restrizioni di accesso in modo che nessuno, compresi i dipendenti AWS, possa accedere ai dati dei clienti in esecuzione in EC2. Il design di sicurezza del sistema Nitro è stato inoltre convalidato in modo indipendente dal gruppo NCC in un report pubblico.
Con AWS i clienti hanno sempre avuto il controllo sulla posizione dei propri dati. I clienti che devono rispettare i requisiti europei di residenza dei dati possono scegliere di distribuire i propri dati in una delle otto regioni AWS esistenti (Irlanda, Francoforte, Londra, Parigi, Stoccolma, Milano, Zurigo e Spagna) per conservare i propri dati in modo sicuro in Europa. Per gestire i propri carichi di lavoro sensibili, i clienti europei possono sfruttare il portafoglio di servizi più ampio e completo, tra cui intelligenza artificiale, analisi ed elaborazione dati, database, Internet of Things (IoT), apprendimento automatico, servizi mobili e storage. Per supportare ulteriormente i clienti, abbiamo introdotto alcune innovazioni per offrire loro maggiore controllo e scelta sulla gestione dei dati. Ad esempio, abbiamo annunciato ulteriore trasparenza e garanzie e nuove opzioni di infrastruttura dedicate con AWS Dedicated Local Zones.
Annuncio AWS European Sovereign Cloud Quando in Europa parliamo con i clienti del settore pubblico e delle industrie regolamentate, riceviamo continue conferme di come si trovano ad affrontare una incredibile complessità e mutevoli dinamiche di un panorama di sovranità in continua evoluzione. I clienti ci dicono che vogliono adottare il cloud, ma si trovano ad affrontare crescenti interventi normativi in relazione alla residenza dei dati, all’autonomia operativa ed alla resilienza europea. Abbiamo appreso che questi clienti temono di dover scegliere tra tutta la potenza di AWS e soluzioni cloud sovrane ma con funzionalità limitate. Abbiamo collaborato intensamente con le autorità di regolamentazione europee, le agenzie nazionali per la sicurezza informatica e i nostri clienti per comprendere come le esigenze di sovranità possano variare in base a molteplici fattori come la residenza, la sensibilità dei carichi di lavoro e il settore. Questi fattori possono influire sui requisiti del carico di lavoro, ad esempio dove possono risiedere i dati, chi può accedervi e i controlli necessari, ed AWS ha una comprovata esperienza di innovazione per affrontare carichi di lavoro specializzati in tutto il mondo.
Oggi siamo lieti di annunciare il nostro programma di lancio dell’AWS European Sovereign Cloud, un nuovo cloud indipendente per l’Europa, progettato per aiutare le organizzazioni del settore pubblico e i clienti in settori altamente regolamentati a soddisfare le loro esigenze di sovranità in continua evoluzione. Stiamo progettando il cloud sovrano europeo AWS in modo che sia separato e indipendente dalle nostre regioni esistenti, con un’infrastruttura situata interamente all’interno dell’Unione Europea (UE), con la stessa sicurezza, disponibilità e prestazioni che i nostri clienti ottengono dalle regioni esistenti oggi. Per garantire una maggiore resilienza operativa all’interno dell’UE, solo i residenti dell’UE che si trovano nell’UE avranno il controllo delle operazioni e il supporto per l’AWS European Sovereign Cloud. Come per tutte le regioni attuali, i clienti che utilizzeranno l’AWS European Sovereign Cloud trarranno vantaggio da tutta la potenza di AWS con la stessa architettura, un ampio portafoglio di servizi e API che milioni di clienti già utilizzano oggi. L’AWS European Sovereign Cloud lancerà la sua prima regione AWS in Germania, disponibile per tutti i clienti europei.
Il cloud sovrano europeo AWS sarà progettato per garantire l’indipendenza operativa e la resilienza all’interno dell’UE e sarà gestito e supportato solamente da dipendenti AWS che si trovano nell’UE e che vi risiedono. Questo design offrirà ai clienti una scelta aggiuntiva per soddisfare le diverse esigenze di residenza dei dati, autonomia operativa e resilienza. Come in tutte le regioni AWS attuali, i clienti che utilizzano l’AWS European Sovereign Cloud trarranno vantaggio da tutta la potenza di AWS, dalla stessa architettura, dall’ampio portafoglio di servizi e dalle stesse API utilizzate oggi da milioni di clienti. L’AWS European Sovereign Cloud lancerà la sua prima regione in Germania.
Il cloud sovrano europeo AWS sarà sovrano by design e si baserà su oltre un decennio di esperienza nella gestione di più cloud indipendenti per carichi di lavoro critici e soggetti a restrizioni. Come le regioni esistenti, il cloud sovrano europeo AWS sarà progettato per garantire disponibilità e resilienza elevate e sarà alimentato da AWS Nitro System per contribuire a garantire la riservatezza e l’integrità dei dati dei clienti. Clienti che avranno il controllo e la garanzia che AWS non potrà accedere od utilizzare i dati dei clienti per alcuno scopo senza il loro consenso. AWS offre ai clienti i controlli di sovranità più rigorosi tra quelli offerti dai principali cloud provider. Per i clienti con esigenze avanzate di residenza dei dati, il cloud sovrano europeo AWS è progettato per andare oltre, e consentirà ai clienti di conservare tutti i metadati che creano (come le etichette dei dati, le categorie, i ruoli degli account e le configurazioni che utilizzano per eseguire AWS) nell’UE. L’AWS European Sovereign Cloud sarà inoltre realizzato con sistemi separati di fatturazione e misurazione dell’utilizzo a livello regionale.
Garantire autonomia operativa L’AWS European Sovereign Cloud fornirà ai clienti la capacità di soddisfare rigorosi requisiti di autonomia operativa e residenza dei dati. Per offrire un maggiore controllo sulla residenza dei dati e sulla resilienza operativa all’interno dell’UE, l’infrastruttura AWS European Sovereign Cloud sarà gestita indipendentemente dalle regioni AWS esistenti. Per garantire il funzionamento indipendente dell’AWS European Sovereign Cloud, solo il personale residente nell’UE, situato nell’UE, avrà il controllo delle operazioni quotidiane, compreso l’accesso ai data center, il supporto tecnico e il servizio clienti.
Stiamo attingendo alle nostre profonde collaborazioni con le autorità di regolamentazione europee e le agenzie nazionali per la sicurezza informatica per applicarle nella realizzazione del cloud sovrano europeo AWS, di modo che i clienti che utilizzano AWS European Sovereign Cloud possano soddisfare i loro requisiti di residenza dei dati, di controllo, di autonomia operativa e resilienza. Ne è un esempio la stretta collaborazione con l’Ufficio federale tedesco per la sicurezza delle informazioni (BSI).
“Lo sviluppo di un cloud AWS europeo renderà molto più semplice l’utilizzo dei servizi AWS per molte organizzazioni del settore pubblico e per aziende con elevati requisiti di sicurezza e protezione dei dati. Siamo consapevoli della forza innovativa dei moderni servizi cloud e vogliamo contribuire a renderli disponibili in modo sicuro per la Germania e l’Europa. Il C5 (Cloud Computing Compliance Criteria Catalogue), sviluppato da BSI, ha plasmato in modo significativo gli standard cloud di sicurezza informatica e AWS è stato infatti il primo fornitore di servizi cloud a ricevere l’attestato C5 di BSI. In questo senso, siamo molto lieti di accompagnare in modo costruttivo lo sviluppo locale di un Cloud AWS, che contribuirà anche alla sovranità europea, in termini di sicurezza”. — Claudia Plattner, Presidente dell’Ufficio federale tedesco per la sicurezza informatica (BSI)
Controllo senza compromessi Sebbene separato, l’AWS European Sovereign Cloud offrirà la stessa architettura leader del settore creata per la sicurezza e la disponibilità delle altre regioni AWS. Ciò includerà multiple zone di disponibilità (AZ) e un’infrastruttura collocata in aree geografiche separate e distinte, con una distanza sufficiente a ridurre in modo significativo il rischio che un singolo evento influisca sulla continuità aziendale dei clienti. Ogni AZ disporrà di più livelli di alimentazione e rete ridondanti per fornire il massimo livello di resilienza. Tutte le AZ del cloud sovrano europeo AWS saranno interconnesse con fibra metropolitana dedicata e completamente ridondata, che fornirà reti ad alta velocità e bassa latenza tra le AZ. Tutto il traffico tra le AZ sarà crittografato. I clienti che necessitano di più opzioni per far fronte ai rigorosi requisiti di isolamento e residenza dei dati all’interno del Paese potranno sfruttare le zone locali dedicate o AWS Outposts per distribuire l’infrastruttura AWS European Sovereign Cloud nelle località da loro selezionate.
Continui investimenti di AWS in Europa L’AWS European Sovereign Cloud è parte del continuo impegno ad investire in Europa di AWS. AWS si impegna a innovare per sostenere i valori europei e il futuro digitale dell’Europa. Promuoviamo lo sviluppo economico investendo in infrastrutture, posti di lavoro e competenze nelle comunità e nei paesi di tutta Europa. Stiamo creando migliaia di posti di lavoro di alta qualità e investendo miliardi di euro nelle economie europee. Amazon ha creato più di 100.000 posti di lavoro permanenti in tutta l’UE. Alcuni dei nostri team di sviluppo AWS più grandi si trovano in Europa, con centri di eccellenza a Dublino, Dresda e Berlino. Nell’ambito del nostro continuo impegno a contribuire allo sviluppo delle competenze digitali, assumeremo e svilupperemo ulteriore personale locale per gestire e supportare l’AWS European Sovereign Cloud.
Clienti, partner e autorità di regolamentazione accolgono con favore il cloud sovrano europeo AWS Nell’UE, centinaia di migliaia di organizzazioni di tutte le dimensioni e in tutti i settori utilizzano AWS, dalle start-up alle piccole e medie imprese, alle grandi imprese, alle società di telecomunicazioni, alle organizzazioni del settore pubblico, agli istituti di istruzione e alle agenzie governative. Organizzazioni di tutta Europa sostengono l’introduzione dell’AWS European Sovereign Cloud.
“In qualità di leader di mercato nel software applicativo aziendale con forti radici in Europa, SAP collabora da tempo con AWS per conto dei clienti per accelerare la trasformazione digitale in tutto il mondo. L’AWS European Sovereign Cloud offre ulteriori opportunità per rafforzare le nostre relazioni in Europa consentendoci di ampliare le scelte che offriamo ai clienti mentre passano al cloud. Apprezziamo la partnership continua con AWS e le nuove possibilità che questo investimento può offrire ai nostri comuni clienti in tutta la regione.” — Peter Pluim, Presidente, SAP Enterprise Cloud Services e SAP Sovereign Cloud Services
“Il nuovo AWS European Sovereign Cloud può rappresentare un punto di svolta per i segmenti di business altamente regolamentati nell’Unione Europea. In qualità di fornitore leader di telecomunicazioni in Germania, la nostra trasformazione digitale si concentra su innovazione, scalabilità, agilità e resilienza per fornire ai nostri clienti i migliori servizi e la migliore qualità. Ciò sarà ora abbinato ai più alti livelli di protezione dei dati e conformità normativa offerti da AWS e con un’attenzione particolare ai requisiti di sovranità digitale. Sono convinto che questa nuova offerta di infrastrutture abbia il potenziale per stimolare l’adozione del cloud da parte delle aziende europee e accelerare la trasformazione digitale delle industrie regolamentate in tutta l’UE”. — Mallik Rao, Chief Technology & Information Officer (CTIO) presso O2 Telefónica in Germania
“Deutsche Telekom accoglie l’annuncio dell’AWS European Sovereign Cloud, che evidenzia l’impegno di AWS a un’innovazione continua nel mercato europeo. Questa soluzione AWS offrirà opportunità important per le aziende e le organizzazioni nell’ambito della migrazione regolamentata sul cloud e opzioni addizionali per soddisfare i requisiti di sovranità digitale europei in continua evoluzione”. — Greg Hyttenrauch, Senior Vice President, Global Cloud Services presso T-Systems
“Oggi siamo al culmine di un’era di trasformazione. L’introduzione dell’AWS European Sovereign Cloud non rappresenta semplicemente un miglioramento infrastrutturale, è un cambio di paradigma. Questo sofisticato framework consentirà a Dedalus di offrire servizi senza precedenti per l’archiviazione dei dati dei pazienti in modo sicuro ed efficiente nel cloud AWS. Rimaniamo impegnati, senza compromessi, a servire la nostra clientela europea con soluzioni best-in-class sostenute da fiducia ed eccellenza tecnologica”. — Andrea Fiumicelli, Presidente di Dedalus
“Noi di de Volksbank crediamo nell’investire per migliorare i Paesi Bassi. Ma perché questo avvenga in modo efficace, dobbiamo avere accesso alle tecnologie più recenti per poter innovare e migliorare continuamente i servizi per i nostri clienti. Per questo motivo, accogliamo con favore l’annuncio dello European Sovereign Cloud che consentirà ai clienti europei di rispettare facilmente la conformità alle normative in evoluzione, beneficiando comunque della scalabilità, della sicurezza e della suite completa dei servizi AWS”. — Sebastiaan Kalshoven, Direttore IT/CTO della Volksbank
“Eviden accoglie con favore il lancio dell’AWS European Sovereign Cloud, che aiuterà le industrie regolamentate e il settore pubblico a soddisfare i requisiti dei loro carichi di lavoro sensibili con un cloud AWS completo e interamente gestito in Europa. In qualità di partner AWS Premier Tier Services e leader nei servizi di sicurezza informatica in Europa, Eviden ha una vasta esperienza nell’aiutare i clienti AWS a formalizzare e mitigare i rischi di sovranità. L’AWS European Sovereign Cloud consentirà a Eviden di soddisfare una gamma più ampia di esigenze di sovranità dei clienti”. — Yannick Tricaud, Responsabile Europa meridionale e centrale, Medio Oriente e Africa, Eviden, Gruppo Atos
“Accogliamo con favore l’impegno di AWS di espandere la propria infrastruttura con un cloud europeo indipendente. Ciò offrirà alle imprese e alle organizzazioni del settore pubblico una scelta più ampia nel soddisfare i requisiti di sovranità digitale. I servizi cloud sono essenziali per la digitalizzazione della pubblica amministrazione. Con l’” Strategia cloud per l’Amministrazione tedesca” e lo standard contrattuale “EVB-IT Cloud”, sono state gettate le basi per l’utilizzo del cloud nella pubblica amministrazione. Sono molto lieto di collaborare con AWS per implementare in modo pratico e collaborativo la sovranità in linea con la nostra strategia cloud.” — Dr. Markus Richter, CIO del governo federale tedesco, Ministero federale degli interni
I nostri impegni nei confronti dei nostri clienti Manteniamo il nostro impegno a fornire ai nostri clienti il controllo e la possibilità di scelta per contribuire a soddisfare le loro esigenze in continua evoluzione in materia di sovranità digitale. Continueremo a innovare le funzionalità, i controlli e le garanzie di sovranità del dato all’interno del cloud AWS globale e a fornirli senza compromessi sfruttando tutta la potenza di AWS.
Compromiso de Soberanía Digital de AWS: anuncio de una nueva nube soberana independiente en la Unión Europea
Desde el primer día, en Amazon Web Services (AWS) siempre hemos creído que es esencial que los clientes tengan el control sobre sus datos y capacidad para proteger y gestionar los mismos en la nube. El año pasado, anunciamos el Compromiso de Soberanía Digital de AWS, nuestra garantía de que ofrecemos a todos los clientes de AWS los controles y funcionalidades de soberanía más avanzados que estén disponibles en la nube. Nos comprometimos a trabajar para comprender las necesidades y los requisitos cambiantes tanto de los clientes como de los reguladores, y a adaptarnos e innovar rápidamente para satisfacerlos. Asimismo, nos comprometimos a ampliar nuestras capacidades para permitir a los clientes satisfacer sus necesidades de soberanía digital sin reducir el rendimiento, la innovación, la seguridad o la escalabilidad de la nube de AWS.
AWS ofrece la infraestructura de nube más amplia y completa del mundo. Nuestro enfoque desde el principio ha sido hacer que AWS sea una nube soberana por diseño. Creamos funcionalidades y controles de protección de datos en la nube de AWS teniendo en cuenta las aportaciones de clientes de sectores como los servicios financieros, sanidad y entidades gubernamentales, que se encuentran entre los más preocupados por la seguridad y la privacidad de los datos en el mundo. Esto ha dado lugar a innovaciones como el sistema Nitro de AWS, que impulsa todas nuestras instancias de Amazon Elastic Compute Cloud (Amazon EC2) y proporciona un límite de seguridad físico y lógico sólido para imponer restricciones de acceso, de modo que nadie, incluidos los empleados de AWS, pueda acceder a los datos de los clientes que se ejecutan en Amazon EC2. El diseño de seguridad del sistema Nitro también ha sido validado de forma independiente por el Grupo NCC en un informe público.
Con AWS, los clientes siempre han tenido el control sobre la ubicación de sus datos. En Europa, los clientes que deben cumplir con los requisitos de residencia de datos europeos tienen la opción de implementar sus datos en cualquiera de las ocho Regiones de AWS existentes (Irlanda, Frankfurt, Londres, París, Estocolmo, Milán, Zúrich y España) para mantener sus datos de forma segura en Europa. Para ejecutar sus cargas de trabajo sensibles, los clientes europeos pueden aprovechar la cartera de servicios más amplia y completa, que incluye inteligencia artificial, análisis, computación, bases de datos, Internet de las cosas (IoT), aprendizaje automático, servicios móviles y almacenamiento. Para apoyar aún más a los clientes, hemos innovado ofreciendo más control y opciones sobre sus datos. Por ejemplo, anunciamos una mayor transparencia y garantías, y nuevas opciones de infraestructura de uso exclusivo con Zonas Locales Dedicadas de AWS.
Anunciamos AWS European Sovereign Cloud Cuando hablamos con clientes del sector público y de sectores regulados en Europa, nos comparten cómo se enfrentan a una gran complejidad y a una dinámica cambiante en el panorama de la soberanía, que está en constante evolución. Los clientes nos dicen que quieren adoptar la nube, pero se enfrentan a un creciente escrutinio regulatorio en relación con la ubicación de los datos, la autonomía operativa europea y la resiliencia. Sabemos que a estos clientes les preocupa tener que elegir entre toda la potencia de AWS o soluciones de nube soberana con funciones limitadas. Hemos mantenido conversaciones muy provechosas con los reguladores europeos, las autoridades nacionales de ciberseguridad y los clientes para entender cómo las necesidades de soberanía de los clientes pueden variar en función de diferentes factores, como la ubicación, la sensibilidad de las cargas de trabajo y el sector. Estos factores pueden impactar en los requisitos aplicables a sus cargas de trabajo, como dónde pueden residir sus datos, quién puede acceder a ellos y los controles necesarios. AWS tiene un historial comprobado de innovación para abordar cargas de trabajo sensibles o especiales en todo el mundo.
Hoy nos complace anunciar nuestros planes de lanzar la Nube Soberana Europea de AWS, una nueva nube independiente para la Unión Europea, diseñada para ayudar a las organizaciones del sector público y a los clientes de sectores altamente regulados a satisfacer sus necesidades de soberanía en constante evolución. Estamos diseñando la Nube Soberana Europea de AWS para que sea independiente y separada de nuestras Regiones actuales, con una infraestructura ubicada íntegramente dentro de la Unión Europea y con la misma seguridad, disponibilidad y rendimiento que nuestros clientes obtienen en las Regiones actuales. Para ofrecer una mayor resiliencia operativa dentro de la UE, solo los residentes de la UE que se encuentren en la UE, tendrán el control de las operaciones y el soporte de la Nube Soberana Europea de AWS. Como ocurre con todas las Regiones actuales, los clientes que utilicen la Nube Soberana Europea de AWS se beneficiarán de toda la potencia de AWS con la misma arquitectura conocida, una amplia cartera de servicios y las APIs que utilizan millones de clientes en la actualidad. La Nube Soberana Europea de AWS lanzará su primera Región de AWS en Alemania disponible para todos los clientes en Europa.
La Nube Soberana Europea de AWS será soberana por diseño y se basará en más de una década de experiencia en la gestión de múltiples nubes independientes para las cargas de trabajo más críticas y restringidas. Al igual que las Regiones existentes, la Nube Soberana Europea de AWS se diseñará para ofrecer una alta disponibilidad y resiliencia, y contará con la tecnología del sistema Nitro de AWS, a fin de garantizar la confidencialidad e integridad de los datos de los clientes. Los clientes tendrán el control y la seguridad de que AWS no accederá a los datos de los clientes ni los utilizará para ningún propósito sin su consentimiento. AWS ofrece a los clientes los controles de soberanía más estrictos entre los principales proveedores de servicios en la nube. Para los clientes con necesidades de residencia de datos mejoradas, la Nube Soberana Europea de AWS está diseñada para ir más allá y permitirá a los clientes conservar todos los metadatos que crean (como funciones, permisos, etiquetas de recursos y configuraciones), las funciones de las cuentas y las configuraciones que utilizan para ejecutar AWS) dentro de la UE. La Nube Soberana Europea de AWS también se construirá con sistemas independientes de facturación y medición del uso dentro de la Región.
Ofreciendo autonomía operativa La Nube Soberana Europea de AWS proporcionará a los clientes la capacidad de cumplir con los estrictos requisitos de autonomía operativa y residencia de datos que sean de aplicación a cada cliente. Para proporcionar una mejor residencia de los datos y resiliencia operativa en la UE, la infraestructura de la Nube Soberana Europea de AWS se gestionará de forma independiente del resto de las Regiones de AWS existentes. Para garantizar el funcionamiento independiente de la Nube Soberana Europea de AWS, solo el personal residente en la UE y ubicado en la UE tendrá el control de las operaciones diarias, incluido el acceso a los centros de datos, el soporte técnico y el servicio de atención al cliente.
Estamos aprendiendo de nuestras intensas conversaciones con los reguladores europeos y las autoridades nacionales de ciberseguridad, aplicando estos aprendizajes a medida que construimos la Nube Soberana Europea de AWS, de modo que los clientes que la utilicen puedan cumplir sus requisitos de residencia, autonomía operativa y resiliencia de los datos. Por ejemplo, esperamos continuar colaborando con la Oficina Federal de Seguridad de la Información (BSI) de Alemania.
«El desarrollo de una nube europea de AWS facilitará mucho el uso de los servicios de AWS a muchas organizaciones y empresas del sector público con altos requisitos de seguridad y protección de datos. Somos conscientes del poder innovador de los servicios en la nube modernos y queremos contribuir a que estén disponibles de forma segura en Alemania y Europa. El C5 (Cloud Computing Compliance Criteria Catalogue), desarrollado por la BSI, ha influido considerablemente en los estándares de ciberseguridad en la nube y, de hecho, AWS fue el primer proveedor de servicios en la nube en recibir el certificado C5 de la BSI. En este sentido, nos complace acompañar de manera constructiva el desarrollo local de una nube de AWS, que también contribuirá a la soberanía europea en términos de seguridad». — Claudia Plattner, presidenta de la Oficina Federal Alemana de Seguridad de la Información (BSI)
Control sin concesiones A pesar de ser independiente, la Nube Soberana Europea de AWS ofrecerá la misma arquitectura líder en el sector que otras Regiones de AWS, creada para garantizar la seguridad y la disponibilidad. Esto incluirá varias Zonas de Disponibilidad, una infraestructura distribuida en ubicaciones geográficas separadas y distintas, con una distancia suficiente para reducir el riesgo de que un incidente afecte a la continuidad del negocio de los clientes. Cada Zona de Disponibilidad tendrá varias fuentes de alimentación eléctrica y redes redundantes para ofrecer el máximo nivel de resiliencia. Todas las Zonas de Disponibilidad de la Nube Soberana Europea de AWS estarán interconectadas mediante fibra de uso exclusivo y totalmente redundante, lo que proporcionará una red de alto rendimiento y baja latencia entre las Zonas de Disponibilidad. Todo el tráfico entre las Zonas de Disponibilidad se encriptará. Los clientes que necesiten más opciones para abordar estrictas necesidades de aislamiento y residencia de datos en el país podrán utilizar las Zonas Locales Dedicadas o AWS Outposts para implementar la infraestructura de Nube Soberana Europea de AWS en las ubicaciones que elijan.
Inversión continua de AWS en Europa La Nube Soberana Europea de AWS representa una inversión continua de AWS en la UE. AWS se compromete a innovar para respaldar los valores y el futuro digital de la Unión Europea. Impulsamos el desarrollo económico mediante la inversión en infraestructura, empleos y habilidades en comunidades y países de toda Europa. Estamos creando miles de puestos de trabajo de alta calidad e invirtiendo miles de millones de euros en las economías europeas. Amazon ha creado más de 100 000 puestos de trabajo permanentes en toda la UE. Algunos de nuestros equipos de desarrollo de AWS más importantes se encuentran en Europa, con centros clave en Dublín, Dresde y Berlín. Como parte de nuestro compromiso continuo de contribuir al desarrollo de las habilidades digitales, contrataremos y capacitaremos a más personal local para gestionar y apoyar la Nube Soberana Europea de AWS.
Los clientes, socios y reguladores dan la bienvenida a la Nube Soberana Europea de AWS En la UE, cientos de miles de organizaciones de todos los tamaños y sectores utilizan AWS, desde startups hasta PYMEs, grandes compañías incluyendo empresas de telecomunicaciones, organizaciones del sector público, instituciones educativas, ONGs y agencias gubernamentales. Organizaciones de toda Europa apoyan la introducción de la Nube Soberana Europea de AWS.
“Como líder del mercado en software de aplicaciones empresariales con sólidas raíces en Europa, SAP lleva colaborando durante mucho tiempo con AWS en nombre de los clientes para acelerar la transformación digital en todo el mundo. La Nube Soberana Europea de AWS ofrece nuevas oportunidades para fortalecer nuestra relación en Europa, ya que nos permite ampliar las opciones que ofrecemos a los clientes a medida que se trasladan a la nube. Valoramos la asociación existente con AWS y las nuevas posibilidades que esta inversión puede ofrecer a los clientes de ambos en toda la región”. – Peter Pluim, Presidente de SAP Enterprise Cloud Services y SAP Sovereign Cloud Services.
“La nueva Nube Soberana Europea de AWS puede cambiar las reglas del juego para los segmentos empresariales altamente regulados de la Unión Europea. Como proveedor de telecomunicaciones líder en Alemania, nuestra transformación digital se centra en la innovación, la escalabilidad, la agilidad y la resiliencia para ofrecer a nuestros clientes los mejores servicios y la mejor calidad. Esto se combinará ahora con los niveles más altos de protección de datos y cumplimiento normativo que ofrece AWS, y con un enfoque particular en los requisitos de soberanía digital. Estoy convencido de que esta nueva oferta de infraestructura tiene el potencial de impulsar la adaptación a la nube de las empresas europeas y acelerar la transformación digital de las industrias reguladas en toda la UE”. — Mallik Rao, Directora de Tecnología e Información de O2 Telefónica en Alemania
“Hoy nos encontramos en la cúspide de una era de transformación. La introducción de la Nube Soberana Europea de AWS no solo representa una mejora de la infraestructura, sino que supone un cambio de paradigma. Este sofisticado marco permitirá a Dedalus ofrecer servicios incomparables para almacenar los datos de los pacientes de forma segura y eficiente en la nube de AWS. Mantenemos nuestro compromiso, sin concesiones, de servir a nuestra clientela europea con las mejores soluciones de su clase respaldadas por la confianza y la excelencia tecnológica”. — Andrea Fiumicelli, Presidente de Dedalus
“En de Volksbank, creemos en invertir en unos Países Bajos mejores. Para hacerlo de manera eficaz, necesitamos tener acceso a las últimas tecnologías para poder innovar y mejorar continuamente los servicios para nuestros clientes. Por este motivo, acogemos con satisfacción el anuncio de la Nube Soberana Europea, que permitirá a los clientes europeos demostrar fácilmente el cumplimiento de las cambiantes normativas y, al mismo tiempo, beneficiarse de la escala, la seguridad y la gama completa de servicios de AWS”. — Sebastian Kalshoven, director de TI y CTO de Volksbank
“Eviden acoge con satisfacción el lanzamiento de la Nube Soberana Europea de AWS. Esto ayudará a las industrias reguladas y al sector público a abordar los requisitos de sus cargas de trabajo confidenciales con una nube de AWS con todas las funciones y que funcione exclusivamente en Europa. Como socio de servicios de primer nivel de AWS y líder en servicios de ciberseguridad en Europa, Eviden tiene una amplia trayectoria ayudando a los clientes de AWS a formalizar y mitigar sus riesgos de soberanía. La Nube Soberana Europea de AWS permitirá a Eviden abordar una gama más amplia de necesidades de soberanía de los clientes”. — Yannick Tricaud, director de Europa Central y Meridional, Oriente Medio y África, de Eviden, del Grupo Atos
Nuestros compromisos con nuestros clientes Mantenemos nuestro compromiso de ofrecer a nuestros clientes el control y las opciones que les ayuden a satisfacer sus necesidades de soberanía digital en constante evolución. Seguiremos innovando en las funcionalidades, los controles y las garantías de soberanía globalmente, y ofreceremos esto sin renunciar a la toda la potencia de AWS.
Puede descubrir más sobre la Nube Soberana Europea de AWS y obtener más información sobre nuestros clientes en nuestra Nota de Prensa y en la web European Digital Sovereignty. También puede obtener más información en AWS News Blog.
In the AWS Security Profile series, I interview some of the humans who work in AWS Security and help keep our customers safe and secure. In this profile, I interviewed Liam Wadman, Senior Solutions Architect for AWS Identity.
Pictured: Liam making quick informed decisions about risk and reward
How long have you been at AWS and what do you do in your current role?
My first day was 1607328000 — for those who don’t speak fluent UTC, that’s December 2020. I’m a member of the Identity Solutions team. Our mission is to make it simpler for customers to implement access controls that protect their data in a straightforward and consistent manner across AWS services.
I spend a lot of time talking with security, identity, and cloud teams at some of our largest and most complex customers, understanding their problems, and working with teams across AWS to make sure that we’re building solutions that meet their diverse security requirements.
I’m a big fan of working with customers and fellow Amazonians on threat modeling and helping them make informed decisions about risks and the controls they put in place. It’s such a productive exercise because many people don’t have that clear model about what they’re protecting, and what they’re protecting it from.
When I work with AWS service teams, I advocate for making services that are simple to secure and simple for customers to configure. It’s not enough to offer only good security controls; the service should be simple to understand and straightforward to apply to meet customer expectations.
How did you get started in security? What about it piqued your interest?
I got started in security at a very young age: by circumventing network controls at my high school so that I could play Flash games circa 2004. Ever since then, I’ve had a passion for deeply understanding a system’s rules and how they can be bent or broken. I’ve been lucky enough to have a diverse set of experiences throughout my career, including working in a network operation center, security operation center, Linux and windows server administration, telephony, investigations, content delivery, perimeter security, and security architecture. I think having such a broad base of experience allows me to empathize with all the different people who are AWS customers on a day-to-day basis.
As I progressed through my career, I became very interested in the psychology of security and the mindsets of defenders, unauthorized users, and operators of computer systems. Security is about so much more than technology—it starts with people and processes.
How do you explain your job to non-technical friends and family?
I get to practice this question a lot! Very few of my family and friends work in tech.
I always start with something relatable to the person. I start with a website, mobile app, or product that they use, tell the story of how it uses AWS, then tie that in around how my team works to support many of the products they use in their everyday lives. You don’t have to look far into our customer success stories or AWS re:Invent presentations to see a product or company that’s meaningful to almost anyone you’d talk to.
I got to practice this very recently because the software used by my personal trainer is hosted on AWS. So when she asked what I actually do for a living, I was ready for her.
In your opinion, what’s the coolest thing happening in identity right now?
You left this question wide open, so I’m going to give you more than one answer.
First, outside of AWS, it’s the rise of ubiquitous, easy-to-use personal identity technology. I’m talking about products such as password managers, sign-in with Google or Apple, and passkeys. I’m excited to see the industry is finally offering services to consumers at no extra cost that you don’t need to be an expert to use and that will work on almost any device you sign in to. Everyday people can benefit from their use, and I have successfully converted many of the people I care about.
At AWS, it’s the work that we’re doing to enable data perimeters and provable security. We hear quite regularly from customers that data perimeters are super important to them, and they want to see us do more in that space and keep refining that journey. I’m all too happy to oblige. Provable security, while identity adjacent, is about getting real answers to questions such as “Can this resource be accessed publicly?” It’s making it simple for customers who don’t want to spend the time or money building the operational expertise to answer tough questions, and I think that’s incredible.
You presented at AWS re:Inforce 2023. What was your session about and what do you hope attendees took away from it?
My session was IAM336: Best practices for delegating access on IAM. I initially delivered this session at re:Inforce 2022, where customers gave it the highest overall rating for an identity session, so we brought it back for 2023!
The talk dives deep into some AWS Identity and Access Management (IAM) primitives and provides a lot of candor on what we feel are best practices based on many of the real-world engagements I’ve had with customers. The top thing that I hope attendees learned is how they can safely empower their developers to have some self service and autonomy when working with IAM and help transform central teams from blockers to enablers.
I’m also presenting at re:Invent 2023 in November. I’ll be doing a chalk talk called Best practices for setting up AWS Organizations policies. We’re targeting it towards a more general audience, not just customers whose primary jobs are AWS security or identity. I’m excited about this presentation because I usually talk to a lot of customers who have very mature security and identity practices, and this is a great chance to get feedback from customers who do not.
I’d like to thank all the customers who attended the sessions over the years — the best part of AWS events is the customer interactions and fantastic discussions that we have.
Is there anything you wish customers would ask about more often?
I wish more customers would frame their problems within a threat model. Many customer engagements start with a specific problem, but it isn’t in the context of the risk this poses to their business, and often focuses too much on specific technical controls for very specific issues, rather than an outcome that they’re trying to arrive at or a risk that they’re trying to mitigate. I like to take a step back and work with the customer to frame the problem that they’re talking about in a bigger picture, then have a more productive conversation around how we can mitigate these risks and other considerations that they may not have thought of.
Where do you see the identity space heading in the future?
I think the industry is really getting ready for an identity renaissance as we start shifting towards more modern and Zero Trust architectures. I’m really excited to start seeing adoption of technologies such as token exchange to help applications avoid impersonating users to downstream systems, or mechanisms such as proof of possession to provide scalable ways to bind a given credential to a system that it’s intended to be used from.
On the AWS Identity side: More controls. Simpler. Scalable. Provable.
What are you most proud of in your career?
Getting involved with speaking at AWS: presenting at summits, re:Inforce, and re:Invent. It’s something I never would have seen myself doing before. I grew up with a pretty bad speech impediment that I’m always working against.
I think my proudest moment in particular is when I had customers come to my re:Invent session because they saw me at AWS Summits earlier in the year and liked what I did there. I get a little emotional thinking about it.
Being a speaker also allowed me to go to Disneyland for the first time last year before the Anaheim Summit, and that would have made 5-year-old Liam proud.
If you had to pick a career outside of tech, what would you want to do?
I think I’d certainly be involved in something in forestry, resource management, or conservation. I spend most of my free time in the forests of British Columbia. I’m a big believer in shinrin-yoku, and I believe in being a good steward of the land. We’ve only got one earth.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
Customers often ask for help with implementing Blue/Green deployments to Amazon Elastic Container Service (Amazon ECS) using AWS CodeDeploy. Their use cases usually involve cross-Region and cross-account deployment scenarios. These requirements are challenging enough on their own, but in addition to those, there are specific design decisions that need to be considered when using CodeDeploy. These include how to configure CodeDeploy, when and how to create CodeDeploy resources (such as Application and Deployment Group), and how to write code that can be used to deploy to any combination of account and Region.
Today, I will discuss those design decisions in detail and how to use CDK Pipelines to implement a self-mutating pipeline that deploys services to Amazon ECS in cross-account and cross-Region scenarios. At the end of this blog post, I also introduce a demo application, available in Java, that follows best practices for developing and deploying cloud infrastructure using AWS Cloud Development Kit (AWS CDK).
The Pipeline
CDK Pipelines is an opinionated construct library used for building pipelines with different deployment engines. It abstracts implementation details that developers or infrastructure engineers need to solve when implementing a cross-Region or cross-account pipeline. For example, in cross-Region scenarios, AWS CloudFormation needs artifacts to be replicated to the target Region. For that reason, AWS Key Management Service (AWS KMS) keys, an Amazon Simple Storage Service (Amazon S3) bucket, and policies need to be created for the secondary Region. This enables artifacts to be moved from one Region to another. In cross-account scenarios, CodeDeploy requires a cross-account role with access to the KMS key used to encrypt configuration files. This is the sort of detail that our customers want to avoid dealing with manually.
AWS CodeDeploy is a deployment service that automates application deployment across different scenarios. It deploys to Amazon EC2 instances, On-Premises instances, serverless Lambda functions, or Amazon ECS services. It integrates with AWS Identity and Access Management (AWS IAM), to implement access control to deploy or re-deploy old versions of an application. In the Blue/Green deployment type, it is possible to automate the rollback of a deployment using Amazon CloudWatch Alarms.
CDK Pipelines was designed to automate AWS CloudFormation deployments. Using AWS CDK, these CloudFormation deployments may include deploying application software to instances or containers. However, some customers prefer using CodeDeploy to deploy application software. In this blog post, CDK Pipelines will deploy using CodeDeploy instead of CloudFormation.
Design Considerations
In this post, I’m considering the use of CDK Pipelines to implement different use cases for deploying a service to any combination of accounts (single-account & cross-account) and regions (single-Region & cross-Region) using CodeDeploy. More specifically, there are four problems that need to be solved:
CodeDeploy Configuration
The most popular options for implementing a Blue/Green deployment type using CodeDeploy are using CloudFormation Hooks or using a CodeDeploy construct. I decided to operate CodeDeploy using its configuration files. This is a flexible design that doesn’t rely on using custom resources, which is another technique customers have used to solve this problem. On each run, a pipeline pushes a container to a repository on Amazon Elastic Container Registry (ECR) and creates a tag. CodeDeploy needs that information to deploy the container.
I recommend creating a pipeline action to scan the AWS CDK cloud assembly and retrieve the repository and tag information. The same action can create the CodeDeploy configuration files. Three configuration files are required to configure CodeDeploy: appspec.yaml, taskdef.json and imageDetail.json. This pipeline action should be executed before the CodeDeploy deployment action. I recommend creating template files for appspec.yaml and taskdef.json. The following script can be used to implement the pipeline action:
##
#!/bin/sh
#
# Action Configure AWS CodeDeploy
# It customizes the files template-appspec.yaml and template-taskdef.json to the environment
#
# Account = The target Account Id
# AppName = Name of the application
# StageName = Name of the stage
# Region = Name of the region (us-east-1, us-east-2)
# PipelineId = Id of the pipeline
# ServiceName = Name of the service. It will be used to define the role and the task definition name
#
# Primary output directory is codedeploy/. All the 3 files created (appspec.json, imageDetail.json and
# taskDef.json) will be located inside the codedeploy/ directory
#
##
Account=$1
Region=$2
AppName=$3
StageName=$4
PipelineId=$5
ServiceName=$6
repo_name=$(cat assembly*$PipelineId-$StageName/*.assets.json | jq -r '.dockerImages[] | .destinations[] | .repositoryName' | head -1)
tag_name=$(cat assembly*$PipelineId-$StageName/*.assets.json | jq -r '.dockerImages | to_entries[0].key')
echo ${repo_name}
echo ${tag_name}
printf '{"ImageURI":"%s"}' "$Account.dkr.ecr.$Region.amazonaws.com/${repo_name}:${tag_name}" > codedeploy/imageDetail.json
sed 's#APPLICATION#'$AppName'#g' codedeploy/template-appspec.yaml > codedeploy/appspec.yaml
sed 's#APPLICATION#'$AppName'#g' codedeploy/template-taskdef.json | sed 's#TASK_EXEC_ROLE#arn:aws:iam::'$Account':role/'$ServiceName'#g' | sed 's#fargate-task-definition#'$ServiceName'#g' > codedeploy/taskdef.json
cat codedeploy/appspec.yaml
cat codedeploy/taskdef.json
cat codedeploy/imageDetail.json
Using a Toolchain
A good strategy is to encapsulate the pipeline inside a Toolchain to abstract how to deploy to different accounts and regions. This helps decoupling clients from the details such as how the pipeline is created, how CodeDeploy is configured, and how cross-account and cross-Region deployments are implemented. To create the pipeline, deploy a Toolchain stack. Out-of-the-box, it allows different environments to be added as needed. Depending on the requirements, the pipeline may be customized to reflect the different stages or waves that different components might require. For more information, please refer to our best practices on how to automate safe, hands-off deployments and its reference implementation.
In detail, the Toolchain stack follows the builder pattern used throughout the CDK for Java. This is a convenience that allows complex objects to be created using a single statement:
In the statement above, the continuous deployment pipeline is created in the TOOLCHAIN_ACCOUNT and TOOLCHAIN_REGION. It implements a stage that builds the source code and creates the Java archive (JAR) using Apache Maven. The pipeline then creates a Docker image containing the JAR file.
The UAT stage will deploy the service to the SERVICE_ACCOUNT and SERVICE_REGION using the deployment configuration CANARY_10_PERCENT_5_MINUTES. This means 10 percent of the traffic is shifted in the first increment and the remaining 90 percent is deployed 5 minutes later.
To create additional deployment stages, you need a stage name, a CodeDeploy deployment configuration and an environment where it should deploy the service. As mentioned, the pipeline is, by default, a self-mutating pipeline. For example, to add a Prod stage, update the code that creates the Toolchain object and submit this change to the code repository. The pipeline will run and update itself adding a Prod stage after the UAT stage. Next, I show in detail the statement used to add a new Prod stage. The new stage deploys to the same account and Region as in the UAT environment:
In the statement above, the Prod stage will deploy new versions of the service using a CodeDeploy deployment configurationCANARY_10_PERCENT_5_MINUTES. It means that 10 percent of traffic is shifted in the first increment of 5 minutes. Then, it shifts the rest of the traffic to the new version of the application. Please refer to Organizing Your AWS Environment Using Multiple Accounts whitepaper for best-practices on how to isolate and manage your business applications.
Some customers might find this approach interesting and decide to provide this as an abstraction to their application development teams. In this case, I advise creating a construct that builds such a pipeline. Using a construct would allow for further customization. Examples are stages that promote quality assurance or deploy the service in a disaster recovery scenario.
The implementation creates a stack for the toolchain and another stack for each deployment stage. As an example, consider a toolchain created with a single deployment stage named UAT. After running successfully, the DemoToolchain and DemoService-UAT stacks should be created as in the next image:
CodeDeploy Application and Deployment Group
CodeDeploy configuration requires an application and a deployment group. Depending on the use case, you need to create these in the same or in a different account from the toolchain (pipeline). The pipeline includes the CodeDeploy deployment action that performs the blue/green deployment. My recommendation is to create the CodeDeploy application and deployment group as part of the Service stack. This approach allows to align the lifecycle of CodeDeploy application and deployment group with the related Service stack instance.
CodePipeline allows to create a CodeDeploy deployment action that references a non-existing CodeDeploy application and deployment group. This allows us to implement the following approach:
Toolchain stack deploys the pipeline with CodeDeploy deployment action referencing a non-existing CodeDeploy application and deployment group
When the pipeline executes, it first deploys the Service stack that creates the related CodeDeploy application and deployment group
The next pipeline action executes the CodeDeploy deployment action. When the pipeline executes the CodeDeploy deployment action, the related CodeDeploy application and deployment will already exist.
Below is the pipeline code that references the (initially non-existing) CodeDeploy application and deployment group.
To make this work, you should use the same application name and deployment group name values when creating the CodeDeploy deployment action in the pipeline and when creating the CodeDeploy application and deployment group in the Service stack (where the Amazon ECS infrastructure is deployed). This approach is necessary to avoid a circular dependency error when trying to create the CodeDeploy application and deployment group inside the Service stack and reference these objects to configure the CodeDeploy deployment action inside the pipeline. Below is the code that uses Service stack construct ID to name the CodeDeploy application and deployment group. I set the Service stack construct ID to the same name I used when creating the CodeDeploy deployment action in the pipeline.
CDK Pipelines creates roles and permissions the pipeline uses to execute deployments in different scenarios of regions and accounts. When using CodeDeploy in cross-account scenarios, CDK Pipelines deploys a cross-account support stack that creates a pipeline action role for the CodeDeploy action. This cross-account support stack is defined in a JSON file that needs to be published to the AWS CDK assets bucket in the target account. If the pipeline has the self-mutation feature on (default), the UpdatePipeline stage will do a cdk deploy to deploy changes to the pipeline. In cross-account scenarios, this deployment also involves deploying/updating the cross-account support stack. For this, the SelfMutate action in UpdatePipeline stage needs to assume CDK file-publishing and a deploy roles in the remote account.
The IAM role associated with the AWS CodeBuild project that runs the UpdatePipeline stage does not have these permissions by default. CDK Pipelines cannot grant these permissions automatically, because the information about the permissions that the cross-account stack needs is only available after the AWS CDK app finishes synthesizing. At that point, the permissions that the pipeline has are already locked-in. Hence, for cross-account scenarios, the toolchain should extend the permissions of the pipeline’s UpdatePipeline stage to include the file-publishing and deploy roles.
In cross-account environments it is possible to manually add these permissions to the UpdatePipeline stage. To accomplish that, the Toolchain stack may be used to hide this sort of implementation detail. In the end, a method like the one below can be used to add these missing permissions. For each different mapping of stage and environment in the pipeline it validates if the target account is different than the account where the pipeline is deployed. When the criteria is met, it should grant permission to the UpdatePipeline stage to assume CDK bootstrap roles (tagged using key aws-cdk:bootstrap-role) in the target account (with the tag value as file-publishing or deploy). The example below shows how to add permissions to the UpdatePipeline stage:
Let’s consider a pipeline that has a single deployment stage, UAT. The UAT stage deploys a DemoService. For that, it requires four actions: DemoService-UAT (Prepare and Deploy), ConfigureBlueGreenDeploy and Deploy.
The DemoService-UAT.Deploy action will create the ECS resources and the CodeDeploy application and deployment group. The ConfigureBlueGreenDeploy action will read the AWS CDK cloud assembly. It uses the configuration files to identify the Amazon Elastic Container Registry (Amazon ECR) repository and the container image tag pushed. The pipeline will send this information to the Deploy action. The Deploy action starts the deployment using CodeDeploy.
Solution Overview
As a convenience, I created an application, written in Java, that solves all these challenges and can be used as an example. The application deployment follows the same 5 steps for all deployment scenarios of account and Region, and this includes the scenarios represented in the following design:
Conclusion
In this post, I identified, explained and solved challenges associated with the creation of a pipeline that deploys a service to Amazon ECS using CodeDeploy in different combinations of accounts and regions. I also introduced a demo application that implements these recommendations. The sample code can be extended to implement more elaborate scenarios. These scenarios might include automated testing, automated deployment rollbacks, or disaster recovery. I wish you success in your transformative journey.
Data governance is the process of ensuring the integrity, availability, usability, and security of an organization’s data. Due to the volume, velocity, and variety of data being ingested in data lakes, it can get challenging to develop and maintain policies and procedures to ensure data governance at scale for your data lake. Data confidentiality and data quality are the two essential themes for data governance. Data confidentiality refers to the protection and control of sensitive and private information to prevent unauthorized access, especially when dealing with personally identifiable information (PII). Data quality focuses on maintaining accurate, reliable, and consistent data across the organization. Poor data quality can lead to erroneous decisions, inefficient operations, and compromised business performance.
Companies need to ensure data confidentiality is maintained throughout the data pipeline and that high-quality data is available to consumers in a timely manner. A lot of this effort is manual, where data owners and data stewards define and apply the policies statically up front for each dataset in the lake. This gets tedious and delays the data adoption across the enterprise.
Let’s consider a fictional company, OkTank. OkTank has multiple ingestion pipelines that populate multiple tables in the data lake. OkTank wants to ensure the data lake is governed with data quality rules and access policies in place at all times.
Multiple personas consume data from the data lake, such as business leaders, data scientists, data analysts, and data engineers. For each set of users, a different level of governance is needed. For example, business leaders need top-quality and highly accurate data, data scientists cannot see PII data and need data within an acceptable quality range for their model training, and data engineers can see all data except PII.
Currently, these requirements are hard-coded and managed manually for each set of users. OkTank wants to scale this and is looking for ways to control governance in an automated way. Primarily, they are looking for the following features:
When new data and tables get added to the data lake, the governance policies (data quality checks and access controls) get automatically applied for them. Unless the data is certified to be consumed, it shouldn’t be accessible to the end-users. For example, they want to ensure basic data quality checks are applied on all new tables and provide access to the data based on the data quality score.
Due to changes in source data, the existing data profile of data lake tables may drift. It’s required to ensure the governance is met as defined. For example, the system should automatically mark columns as sensitive if sensitive data is detected in a column that was earlier marked as public and was available publicly for users. The system should hide the column from unauthorized users accordingly.
For the purpose of this post, the following governance policies are defined:
No PII data should exist in tables or columns tagged as public.
If a column has any PII data, the column should be marked as sensitive. The table should then also be marked sensitive.
The following data quality rules should be applied on all tables:
All tables should have a minimum set of columns: data_key, data_load_date, and data_location.
data_key is a key column and should meet key requirements of being unique and complete.
data_location should match with locations defined in a separate reference (base) table.
The data_load_date column should be complete.
User access to tables is controlled as per the following table.
User Description
Can Access Sensitive Tables
Can Access Sensitive Columns
Min Data Quality Threshold Needed to consume Data
Category 1
Yes
Yes
100%
Category 2
Yes
No
50%
Category 3
No
No
0%
In this post, we use AWS Glue Data Quality and sensitive data detection features. We also use Lake Formation tag-based access control to manage access at scale.
The following diagram illustrates the solution architecture.
The governance requirements highlighted in the previous table are translated to the following Lake Formation LF-Tags.
IAM User
LF-Tag: tbl_class
LF-Tag: col_class
LF-Tag: dq_tag
Category 1
sensitive, public
sensitive, public
DQ100
Category 2
sensitive, public
public
DQ100,DQ90,DQ50_80,DQ80_90
Category 3
public
public
DQ90, DQ100, DQ_LT_50, DQ50_80, DQ80_90
This post uses AWS Step Functions to orchestrate the governance jobs, but you can use any other orchestration tool of choice. To simulate data ingestion, we manually place the files in an Amazon Simple Storage Service (Amazon S3) bucket. In this post, we trigger the Step Functions state machine manually for ease of understanding. In practice, you can integrate or invoke the jobs as part of a data ingestion pipeline, via event triggers like AWS Glue crawler or Amazon S3 events, or schedule them as needed.
In this post, we use an AWS Glue database named oktank_autogov_temp and a target table named customer on which we apply the governance rules. We use AWS CloudFormation to provision the resources. AWS CloudFormation lets you model, provision, and manage AWS and third-party resources by treating infrastructure as code.
Prerequisites
Complete the following prerequisite steps:
Identify an AWS Region in which you want to create the resources and ensure you use the same Region throughout the setup and verifications.
Have a Lake Formation administrator role to run the CloudFormation template and grant permissions.
Sign in to the Lake Formation console and add yourself as a Lake Formation data lake administrator if you aren’t already an admin. If you are setting up Lake Formation for the first time in your Region, then you can do this in the following pop-up window that appears up when you connect to the Lake Formation console and select the desired Region.
Otherwise, you can add data lake administrators by choosing Administrative roles and tasks in the navigation pane on the Lake Formation console and choosing Add administrators. Then select Data lake administrator, identity your users and roles, and choose Confirm.
You need to provide a unique bucket name and specify passwords for the three users reflecting three different user personas (Category 1, Category 2, and Category 3) that we use for this post.
The stack provisions an S3 bucket to store the dummy data, AWS Glue scripts, results of sensitive data detection, and Amazon Athena query results in their respective folders.
The stack copies the AWS Glue scripts into the scripts folder and creates two AWS Glue jobs Data-Quality-PII-Checker_Job and LF-Tag-Handler_Job pointing to the corresponding scripts.
The AWS Glue job Data-Quality-PII-Checker_Job applies the data quality rules and publishes the results. It also checks for sensitive data in the columns. In this post, we check for the PERSON_NAME and EMAILdata types. If any columns with sensitive data are detected, it persists the sensitive data detection results to the S3 bucket.
The following screenshot shows a sample result from the job after it runs. You can see this after you trigger the Step Functions workflow in subsequent steps. To check the results, on the AWS Glue console, choose ETL jobs and choose the job called Data-Quality-PII-Checker_Job. Then navigate to the Data quality tab to view the results.
The AWS Glue jobLF-Tag-Handler_Job fetches the data quality metrics published by Data-Quality-PII-Checker_Job. It checks the status of the DataQuality_PIIColumns result. It gets the list of sensitive column names from the sensitive data detection file created in the Data-Quality-PII-Checker_Job and tags the columns as sensitive. The rest of the columns are tagged as public. It also tags the table assensitive if sensitive columns are detected. The table is marked as public if no sensitive columns are detected.
The job also checks the data quality score for the DataQuality_BasicChecks result set. It maps the data quality score into tags as shown in the following table and applies the corresponding tag on the table.
Data Quality Score
Data Quality Tag
100%
DQ100
90-100%
DQ90
80-90%
DQ80_90
50-80%
DQ50_80
Less than 50%
DQ_LT_50
The CloudFormation stack copies some mock data to the data folder and registers this location under AWS Lake Formation Data lake locations so Lake Formation can govern access on the location using service-linked role for Lake Formation.
The customer subfolder contains the initial customer dataset for the table customer. The base subfolder contains the base dataset, which we use to check referential integrity as part of the data quality checks. The column data_location in the customer table should match with locations defined in this base table.
The stack also copies some additional mock data to the bucket under the data-v1 folder. We use this data to simulate data quality issues.
It also creates the following resources:
An AWS Glue database called oktank_autogov_temp and two tables under the database:
customer – This is our target table on which we will be governing the access based on data quality rules and PII checks.
base – This is the base table that has the reference data. One of the data quality rules checks that the customer data always adheres to locations present in the base table.
DataLakeUser_Category1 – The data lake user corresponding to the Category 1 user. This user should be able to access sensitive data but needs 100% accurate data.
DataLakeUser_Category2 – The data lake user corresponding to the Category 2 user. This user should not be able to access sensitive columns in the table. It needs more than 50% accurate data.
DataLakeUser_Category3 – The data lake user corresponding to the Category 3 user. This user should not be able to access tables containing sensitive data. Data quality can be 0%.
GlueServiceDQRole – The role for the data quality and sensitive data detection job.
GlueServiceLFTaggerRole – The role for the LF-Tags handler job for applying the tags to the table.
StepFunctionRole – The Step Functions role for triggering the AWS Glue jobs.
A Step Functions state machine named AutoGovMachine that you use to trigger the runs for the AWS Glue jobs to check data quality and update the LF-Tags.
Athena workgroups named auto_gov_blog_workgroup_temporary_user1, auto_gov_blog_workgroup_temporary_user2, and auto_gov_blog_workgroup_temporary_user3. These workgroups point to different Athena query result locations for each user. Each user is granted access to the corresponding query result location only. This ensures a specific user doesn’t access the query results of other users. You should switch to a specific workgroup to run queries in Athena as part of the test for the specific user.
The CloudFormation stack generates the following outputs. Take note of the values of the IAM users to use in subsequent steps.
Grant permissions
After you launch the CloudFormation stack, complete the following steps:
On the Lake Formation console, under Permissions choose Data lake permissions in the navigation pane.
Search for the database oktank_autogov_temp and table customer.
If IAMAllowedPrincipals access if present, select it choose Revoke.
Choose Revoke again to revoke the permissions.
Category 1 users can access all data except if the data quality score of the table is below 100%. Therefore, we grant the user the necessary permissions.
Under Permissions in the navigation pane, choose Data lake permissions.
Search for database oktank_autogov_temp and table customer.
Choose Grant
Select IAM users and roles and choose the value for UserCategory1 from your CloudFormation stack output.
Under LF-Tags or catalog resources, choose Add LF-Tag key-value pair.
Add the following key-value pairs:
For the col_class key, add the values public and sensitive.
For the tbl_class key, add the values public and sensitive.
For the dq_tag key, add the value DQ100.
For Table permissions, select Select.
Choose Grant.
Category 2 users can’t access sensitive columns. They can access tables with a data quality score above 50%.
Repeat the preceding steps to grant the appropriate permissions in Lake Formation to UserCategory2:
For the col_class key, add the value public.
For the tbl_class key, add the values public and sensitive.
For the dq_tag key, add the values DQ50_80, DQ80_90, DQ90, and DQ100.
For Table permissions, select Select.
Choose Grant.
Category 3 users can’t access tables that contain any sensitive columns. Such tables are marked as sensitive by the system. They can access tables with any data quality score.
Repeat the preceding steps to grant the appropriate permissions in Lake Formation to UserCategory3:
For the col_class key, add the value public.
For the tbl_class key, add the value public.
For the dq_tag key, add the values DQ_LT_50, DQ50_80, DQ80_90, DQ90, and DQ100.
For Table permissions, select Select.
Choose Grant.
You can verify the LF-Tag permissions assigned in Lake Formation by navigating to the Data lake permissions page and searching for the Resource type LF-Tag expression.
Test the solution
Now we can test the workflow. We test three different use cases in this post. You will notice how the permissions to the tables change based on the values of LF-Tags applied to the customer table and the columns of the table. We use Athena to query the tables.
Use case 1
In this first use case, a new table was created on the lake and new data was ingested to the table. The data file cust_feedback_v0.csv was copied to the data/customer location in the S3 bucket. This simulates new data ingestion on a new table called customer.
Lake Formation doesn’t allow any users to access this table currently. To test this scenario, complete the following steps:
Sign in to the Athena console with the UserCategory1 user.
Switch the workgroup to auto_gov_blog_workgroup_temporary_user1 in the Athena query editor.
Choose Acknowledge to accept the workgroup settings.
Run the following query in the query editor:
select * from "oktank_autogov_temp"."customer" limit 10
On the Step Functions console, run the AutoGovMachine state machine.
In the Input – optional section, use the following JSON and replace the BucketName value with the bucket name you used for the CloudFormation stack earlier (for this post, we use auto-gov-blog):
{
  "Comment": "Auto Governance with AWS Glue and AWS LakeFormation",
  "BucketName": "<Replace with your bucket name>"
}
The state machine triggers the AWS Glue jobs to check data quality on the table and apply the corresponding LF-Tags.
You can check the LF-Tags applied on the table and the columns. To do so, when the state machine is complete, sign in to Lake Formation with the admin role used earlier to grant permissions.
Navigate to the table customer under the oktank_autogov_temp database and choose Edit LF-Tags to validate the tags applied on the table.
You can also validate that columns customer_email and customer_name are tagged as sensitive for the col_class LF-Tag.
To check this, choose Edit Schema for the customer table.
Select the two columns and choose Edit LF-Tags.
You can check the tags on these columns.
The rest of the columns are tagged as public.
Sign in to the Athena console with UserCategory1 and run the same query again:
select * from "oktank_autogov_temp"."customer" limit 10
This time, the user is able to see the data. This is because the LF-Tag permissions we applied earlier are in effect.
Sign in as UserCategory2 user to verify permissions.
Switch to workgroup auto_gov_blog_workgroup_temporary_user2 in Athena.
This user can access the table but can only see public columns. Therefore, the user shouldn’t be able to see the customer_email and customer_phone columns because these columns contain sensitive data as identified by the system.
Run the same query again:
select * from "oktank_autogov_temp"."customer" limit 10
Sign in to Athena and verify the permissions for DataLakeUser_Category3.
Switch to workgroup auto_gov_blog_workgroup_temporary_user3 in Athena.
This user can’t access the table because the table is marked as sensitive due to the presence of sensitive data columns in the table.
Run the same query again:
select * from "oktank_autogov_temp"."customer" limit 10
Use case 2
Let’s ingest some new data on the table.
Sign in to the Amazon S3 console with the admin role used earlier to grant permissions.
Copy the file cust_feedback_v1.csv from the data-v1 folder in the S3 bucket to the data/customer folder in the S3 bucket using the default options.
This new data file has data quality issues because the column data_location breaks referential integrity with the base table. This data also introduces some sensitive data in column comment1. This column was earlier marked as public because it didn’t have any sensitive data.
The following screenshot shows what the customer folder should look like now.
Run the AutoGovMachine state machine again and use the same JSON as the StartExecution input you used earlier:
{
  "Comment": "Auto Governance with AWS Glue and AWS LakeFormation",
  "BucketName": "<Replace with your bucket name>"
}
The job classifies column comment1 as sensitive on the customer table. It also updates the dq_tag value on the table because the data quality has changed due to the breaking referential integrity check.
You can verify the new tag values via the Lake Formation console as described earlier. The dq_tag value was DQ100. The value is changed to DQ50_80, reflecting the data quality score for the table.
Also, earlier the value for the col_class tag for the comment1 column was public. The value is now changed to sensitive because sensitive data is detected in this column.
Category 2 users shouldn’t be able to access sensitive columns in the table.
Sign in with UserCategory2 to Athena and rerun the earlier query:
select * from "oktank_autogov_temp"."customer" limit 10
The column comment1 is now not available for UserCategory2 as expected. The access permissions are handled automatically.
Also, because the data quality score goes down below 100%, this new dataset is now not available for the Category1 user. This user should have access to data only when the score is 100% as per our defined rules.
Sign in with UserCategory1 to Athena and rerun the earlier query:
select * from "oktank_autogov_temp"."customer" limit 10
You will see the user is not able to access the table now. The access permissions are handled automatically.
Use case 3
Let’s fix the invalid data and remove the data quality issue.
Delete the cust_feedback_v1.csv file from the data/customer Amazon S3 location.
Copy the file cust_feedback_v1_fixed.csv from the data-v1 folder in the S3 bucket to the data/customer S3 location. This data file fixes the data quality issues.
Rerun the AutoGovMachine state machine.
When the state machine is complete, the data quality score goes up to 100% again and the tag on the table gets updated accordingly. You can verify the new tag as shown earlier via the Lake Formation console.
The Category1 user can access the table again.
Clean up
To avoid incurring further charges, delete the CloudFormation stack to delete the resources provisioned as part of this post.
Conclusion
This post covered AWS Glue Data Quality and sensitive detection features and Lake Formation LF-Tag based access control. We explored how you can combine these features and use them to build a scalable automated data governance capability on your data lake. We explored how user permissions changed when data was initially ingested to the table and when data drift was observed as part of subsequent ingestions.
For further reading, refer to the following resources:
Shoukat Ghouse is a Senior Big Data Specialist Solutions Architect at AWS. He helps customers around the world build robust, efficient and scalable data platforms on AWS leveraging AWS analytics services like AWS Glue, AWS Lake Formation, Amazon Athena and Amazon EMR.
At Amazon Web Services (AWS), security is our top priority. Security is deeply embedded into our culture, processes, and systems; it permeates everything we do. What does this mean for you? We believe customers can benefit from learning more about what AWS is doing to prevent and mitigate customer-impacting security events.
Since late August 2023, AWS has detected and been protecting customer applications from a new type of distributed denial of service (DDoS) event. DDoS events attempt to disrupt the availability of a targeted system, such as a website or application, reducing the performance for legitimate users. Examples of DDoS events include HTTP request floods, reflection/amplification attacks, and packet floods. The DDoS events AWS detected were a type of HTTP/2 request flood, which occurs when a high volume of illegitimate web requests overwhelms a web server’s ability to respond to legitimate client requests.
Between August 28 and August 29, 2023, proactive monitoring by AWS detected an unusual spike in HTTP/2 requests to Amazon CloudFront, peaking at over 155 million requests per second (RPS). Within minutes, AWS determined the nature of this unusual activity and found that CloudFront had automatically mitigated a new type of HTTP request flood DDoS event, now called an HTTP/2 rapid reset attack. Over those two days, AWS observed and mitigated over a dozen HTTP/2 rapid reset events, and through the month of September, continued to see this new type of HTTP/2 request flood. AWS customers who had built DDoS-resilient architectures with services like Amazon CloudFront and AWS Shield were able to protect their applications’ availability.
Figure 1. Global HTTP requests per second, September 13 – 16
Overview of HTTP/2 rapid reset attacks
HTTP/2 allows for multiple distinct logical connections to be multiplexed over a single HTTP session. This is a change from HTTP 1.x, in which each HTTP session was logically distinct. HTTP/2 rapid reset attacks consist of multiple HTTP/2 connections with requests and resets in rapid succession. For example, a series of requests for multiple streams will be transmitted followed up by a reset for each of those requests. The targeted system will parse and act upon each request, generating logs for a request that is then reset, or cancelled, by a client. The system performs work generating those logs even though it doesn’t have to send any data back to a client. A bad actor can abuse this process by issuing a massive volume of HTTP/2 requests, which can overwhelm the targeted system, such as a website or application.
Keep in mind that HTTP/2 rapid reset attacks are just a new type of HTTP request flood. To defend against these sorts of DDoS attacks, you can implement an architecture that helps you specifically detect unwanted requests as well as scale to absorb and block those malicious HTTP requests.
Building DDoS resilient architectures
As an AWS customer, you benefit from both the security built into the global cloud infrastructure of AWS as well as our commitment to continuously improve the security, efficiency, and resiliency of AWS services. For prescriptive guidance on how to improve DDoS resiliency, AWS has built tools such as the AWS Best Practices for DDoS Resiliency. It describes a DDoS-resilient reference architecture as a guide to help you protect your application’s availability. While several built-in forms of DDoS mitigation are included automatically with AWS services, your DDoS resilience can be improved by using an AWS architecture with specific services and by implementing additional best practices for each part of the network flow between users and your application.
For example, you can use AWS services that operate from edge locations, such as Amazon CloudFront, AWS Shield, Amazon Route 53, and Route 53 Application Recovery Controller to build comprehensive availability protection against known infrastructure layer attacks. These services can improve the DDoS resilience of your application when serving any type of application traffic from edge locations distributed around the world. Your application can be on-premises or in AWS when you use these AWS services to help you prevent unnecessary requests reaching your origin servers. As a best practice, you can run your applications on AWS to get the additional benefit of reducing the exposure of your application endpoints to DDoS attacks and to protect your application’s availability and optimize the performance of your application for legitimate users. You can use Amazon CloudFront (and its HTTP caching capability), AWS WAF, and Shield Advanced automatic application layer protection to help prevent unnecessary requests reaching your origin during application layer DDoS attacks.
Putting our knowledge to work for AWS customers
AWS remains vigilant, working to help prevent security issues from causing disruption to your business. We believe it’s important to share not only how our services are designed, but also how our engineers take deep, proactive ownership of every aspect of our services. As we work to defend our infrastructure and your data, we look for ways to help protect you automatically. Whenever possible, AWS Security and its systems disrupt threats where that action will be most impactful; often, this work happens largely behind the scenes. We work to mitigate threats by combining our global-scale threat intelligence and engineering expertise to help make our services more resilient against malicious activities. We’re constantly looking around corners to improve the efficiency and security of services including the protocols we use in our services, such as Amazon CloudFront, as well as AWS security tools like AWS WAF, AWS Shield, and Amazon Route 53 Resolver DNS Firewall.
In addition, our work extends security protections and improvements far beyond the bounds of AWS itself. AWS regularly works with the wider community, such as computer emergency response teams (CERT), internet service providers (ISP), domain registrars, or government agencies, so that they can help disrupt an identified threat. We also work closely with the security community, other cloud providers, content delivery networks (CDNs), and collaborating businesses around the world to isolate and take down threat actors. For example, in the first quarter of 2023, we stopped over 1.3 million botnet-driven DDoS attacks, and we traced back and worked with external parties to dismantle the sources of 230 thousand L7/HTTP DDoS attacks. The effectiveness of our mitigation strategies relies heavily on our ability to quickly capture, analyze, and act on threat intelligence. By taking these steps, AWS is going beyond just typical DDoS defense, and moving our protection beyond our borders. To learn more behind this effort, please read How AWS threat intelligence deters threat actors.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
Organizations are grappling with the ever-expanding spectrum of data formats in today’s data-driven landscape. From Avro’s binary serialization to the efficient and compact structure of Protobuf, the landscape of data formats has expanded far beyond the traditional realms of CSV and JSON. As organizations strive to derive insights from these diverse data streams, the challenge lies in seamlessly integrating them into a scalable solution.
In this post, we dive into Amazon Redshift Streaming Ingestion to ingest, process, and analyze non-JSON data formats. Amazon Redshift Streaming Ingestion allows you to connect to Amazon Kinesis Data Streams and Amazon Managed Streaming for Apache Kafka (Amazon MSK) directly through materialized views, in real time and without the complexity associated with staging the data in Amazon Simple Storage Service (Amazon S3) and loading it into the cluster. These materialized views not only provide a landing zone for streaming data, but also offer the flexibility of incorporating SQL transforms and blending into your extract, load, and transform (ELT) pipeline for enhanced processing. For a deeper exploration on configuring and using streaming ingestion in Amazon Redshift, refer to Real-time analytics with Amazon Redshift streaming ingestion.
JSON data in Amazon Redshift
Amazon Redshift enables storage, processing, and analytics on JSON data through the SUPER data type, PartiQL language, materialized views, and data lake queries. The base construct to access streaming data in Amazon Redshift provides metadata from the source stream (attributes like stream timestamp, sequence numbers, refresh timestamp, and more) and the raw binary data from the stream itself. For streams that contain the raw binary data encoded in JSON format, Amazon Redshift provides a variety of tools for parsing and managing the data. For more information about the metadata of each stream format, refer to Getting started with streaming ingestion from Amazon Kinesis Data Streams and Getting started with streaming ingestion from Amazon Managed Streaming for Apache Kafka.
At the most basic level, Amazon Redshift allows parsing the raw data into distinct columns. The JSON_EXTRACT_PATH_TEXT and JSON_EXTRACT_ARRAY_ELEMENT_TEXT functions enable the extraction of specific details from JSON objects and arrays, transforming them into separate columns for analysis. When the structure of the JSON documents and specific reporting requirements are defined, these methods allow for pre-computing a materialized view with the exact structure needed for reporting, with improved compression and sorting for analytics.
In addition to this approach, the Amazon Redshift JSON functions allow storing and analyzing the JSON data in its original state using the adaptable SUPER data type. The function JSON_PARSE allows you to extract the binary data in the stream and convert it into the SUPER data type. With the SUPER data type and PartiQL language, Amazon Redshift extends its capabilities for semi-structured data analysis. It uses the SUPER data type for JSON data storage, offering schema flexibility within a column. For more information on using the SUPER data type, refer to Ingesting and querying semistructured data in Amazon Redshift. This dynamic capability simplifies data ingestion, storage, transformation, and analysis of semi-structured data, enriching insights from diverse sources within the Redshift environment.
Streaming data formats
Organizations using alternative serialization formats must explore different deserialization methods. In the next section, we dive into the optimal approach for deserialization. In this section, we take a closer look at the diverse formats and strategies organizations use to effectively manage their data. This understanding is key in determining the data parsing approach in Amazon Redshift.
Many organizations use a format other than JSON for their streaming use cases. JSON is a self-describing serialization format, where the schema of the data is stored alongside the actual data itself. This makes JSON flexible for applications, but this approach can lead to increased data transmission between applications due to the additional data contained in the JSON keys and syntax. Organizations seeking to optimize their serialization and deserialization performance, and their network communication between applications, may opt to use a format like Avro, Protobuf, or even a custom proprietary format to serialize application data into binary format in an optimized way. This provides the advantage of an efficient serialization where only the message values are packed into a binary message. However, this requires the consumer of the data to know what schema and protocol was used to serialize the data to deserialize the message. There are several ways that organizations can solve this problem, as illustrated in the following figure.
Embedded schema
In an embedded schema approach, the data format itself contains the schema information alongside the actual data. This means that when a message is serialized, it includes both the schema definition and the data values. This allows anyone receiving the message to directly interpret and understand its structure without needing to refer to an external source for schema information. Formats like JSON, MessagePack, and YAML are examples of embedded schema formats. When you receive a message in this format, you can immediately parse it and access the data with no additional steps.
Assumed schema
In an assumed schema approach, the message serialization contains only the data values, and there is no schema information included. To interpret the data correctly, the receiving application needs to have prior knowledge of the schema that was used to serialize the message. This is typically achieved by associating the schema with some identifier or context, like a stream name. When the receiving application reads a message, it uses this context to retrieve the corresponding schema and then decodes the binary data accordingly. This approach requires an additional step of schema retrieval and decoding based on context. This generally requires setting up a mapping in-code or in an external database so that consumers can dynamically retrieve the schemas based on stream metadata (such as the AWS Glue Schema Registry).
One drawback of this approach is in tracking schema versions. Although consumers can identify the relevant schema from the stream name, they can’t identify the particular version of the schema that was used. Producers need to ensure that they are making backward-compatible changes to schemas to ensure consumers aren’t disrupted when using a different schema version.
Embedded schema ID
In this case, the producer continues to serialize the data in binary format (like Avro or Protobuf), similar to the assumed schema approach. However, an additional step is involved: the producer adds a schema ID at the beginning of the message header. When a consumer processes the message, it starts by extracting the schema ID from the header. With this schema ID, the consumer then fetches the corresponding schema from a registry. Using the retrieved schema, the consumer can effectively parse the rest of the message. For example, the AWS Glue Schema Registry provides Java SDK SerDe libraries, which can natively serialize and deserialize messages in a stream using embedded schema IDs. Refer to How the schema registry works for more information about using the registry.
The usage of an external schema registry is common in streaming applications because it provides a number of benefits to consumers and developers. This registry contains all the message schemas for the applications and associates them with a unique identifier to facilitate schema retrieval. In addition, the registry may provide other functionalities like schema version change handling and documentation to facilitate application development.
The embedded schema ID in the message payload can contain version information, ensuring publishers and consumers are always using the same schema version to manage data. When schema version information isn’t available, schema registries can help enforce producers making backward-compatible changes to avoid causing issues in consumers. This helps decouple producers and consumers, provides schema validation at both the publisher and consumer stage, and allows for more flexibility in stream usage to allow for a variety of application requirements. Messages can be published with one schema per stream, or with multiple schemas inside a single stream, allowing consumers to dynamically interpret messages as they arrive.
For batch processing use cases, applications may embed the schema used to serialize the data into the data file itself to facilitate data consumption. This is an extension of the embedded schema approach but is less costly because the data file is generally larger, so the schema accounts for a proportionally smaller amount of the overall data. In this case, the consumers can process the data directly without additional logic. Amazon Redshift supports loading Avro data that has been serialized in this manner using the COPY command.
Convert non-JSON data to JSON
Organizations aiming to use non-JSON serialization formats need to develop an external method for parsing their messages outside of Amazon Redshift. We recommend using an AWS Lambda-based external user-defined function (UDF) for this process. Using an external Lambda UDF allows organizations to define arbitrary deserialization logic to support any message format, including embedded schema, assumed schema, and embedded schema ID approaches. Although Amazon Redshift supports defining Python UDFs natively, which may be a viable alternative for some use cases, we demonstrate the Lambda UDF approach in this post to cover more complex scenarios. For examples of Amazon Redshift UDFs, refer to AWS Samples on GitHub.
The basic architecture for this solution is as follows.
See the following code:
-- Step 1
CREATE OR REPLACE EXTERNAL FUNCTION fn_lambda_decode_avro_binary(varchar)
RETURNS varchar IMMUTABLE LAMBDA 'redshift-avro-udf';

-- Step 2
CREATE EXTERNAL SCHEMA kds FROM KINESIS

-- Step 3
CREATE MATERIALIZED VIEW {name} AUTO REFRESH YES AS
SELECT
    -- Step 4
   t.kinesis_data AS binary_avro,
   to_hex(binary_avro) AS hex_avro,
   -- Step 5
   fn_lambda_decode_avro_binary('{stream-name}', hex_avro) AS json_string,
   -- Step 6
   JSON_PARSE(json_string) AS super_data,
   t.sequence_number,
   t.refresh_time,
   t.approximate_arrival_timestamp,
   t.shard_id
FROM kds.{stream_name} AS t
Let’s explore each step in more detail.
Create the Lambda UDF
The overall goal is to develop a method that can accept the raw data as input and produce JSON-encoded data as an output. This aligns with the Amazon Redshift ability to natively process JSON into the SUPER data type. The specifics of the function depend on the serialization and streaming approach. For example, using the assumed schema approach with Avro format, your Lambda function may complete the following steps:
Take in the stream name and hexadecimal-encoded data as inputs.
Use the stream name to perform a lookup to identify the schema for the given stream name.
Decode the hexadecimal data into binary format.
Use the schema to deserialize the binary data into readable format.
Re-serialize the data into JSON format.
The f_glue_schema_registry_avro_to_json AWS samples example illustrates the process of decoding Avro using the assumed schema approach using the AWS Glue Schema Registry in a Lambda UDF to retrieve and use Avro schemas by stream name. For other approaches (such as embedded schema ID), you should author your Lambda function to handle deserialization as defined by your serialization process and schema registry implementation. If your application depends on an external schema registry or table lookup to process the message schema, we recommend that you implement caching for schema lookups to help reduce the load on the external systems and reduce the average Lambda function invocation duration.
When creating the Lambda function, make sure you accommodate the Amazon Redshift input event format and ensure compliance with the expected Amazon Redshift event output format. For details, refer to Creating a scalar Lambda UDF.
After you create and test the Lambda function, you can define it as a UDF in Amazon Redshift. For effective integration within Amazon Redshift, designate this Lambda function UDF as IMMUTABLE. This classification supports incremental materialized view updates. This treats the Lambda function as idempotent and minimizes the Lambda function costs for the solution, because a message doesn’t need to be processed if it has been processed before.
Configure the baseline Kinesis data stream
Regardless of your messaging format or approach (embedded schema, assumed schema, and embedded schema ID), you begin with setting up the external schema for streaming ingestion from your messaging source into Amazon Redshift. For more information, refer to Streaming ingestion.
CREATE EXTERNAL SCHEMA kds FROM KINESIS

IAM_ROLE 'arn:aws:iam::0123456789:role/redshift-streaming-role';
Create the raw materialized view
Next, you define your raw materialized view. This view contains the raw message data from the streaming source in Amazon Redshift VARBYTE format.
Convert the VARBYTE data to VARCHAR format
External Lambda function UDFs don’t support VARBYTE as an input data type. Therefore, you must convert the raw VARBYTE data from the stream into VARCHAR format to pass to the Lambda function. The best way to do this in Amazon Redshift is using the TO_HEX built-in method. This converts the binary data into hexadecimal-encoded character data, which can be sent to the Lambda UDF.
Invoke the Lambda function to retrieve JSON data
After the UDF has been defined, we can invoke the UDF to convert our hexadecimal-encoded data into JSON-encoded VARCHAR data.
Use the JSON_PARSE method to convert the JSON data to SUPER data type
Finally, we can use the Amazon Redshift native JSON parsing methods like JSON_PARSE, JSON_EXTRACT_PATH_TEXT, and more to parse the JSON data into a format that we can use for analytics.
Considerations
Consider the following when using this strategy:
Cost – Amazon Redshift invokes the Lambda function in batches to improve scalability and reduce the overall number of Lambda invocations. The cost of this solution depends on the number of messages in your stream, the frequency of the refresh, and the invocation time required to process the messages in a batch from Amazon Redshift. Using the IMMUTABLE UDF type in Amazon Redshift can also help minimize costs by utilizing the incremental refresh strategy for the materialized view.
Permissions and network access – The AWS Identity and Access Management (IAM) role used for the Amazon Redshift UDF must have permissions to invoke the Lambda function, and you must deploy the Lambda function such that it has access to invoke its external dependencies (for example, you may need to deploy it in a VPC to access private resources like a schema registry).
In this post, we dove into different data formats and ingestion methods for a streaming use case. By exploring strategies for handling non-JSON data formats, we examined the use of Amazon Redshift streaming to seamlessly ingest, process, and analyze these formats in near-real time using materialized views.
Furthermore, we navigated through schema-per-stream, embedded schema, assumed schema, and embedded schema ID approaches, highlighting their merits and considerations. To bridge the gap between non-JSON formats and Amazon Redshift, we explored the creation of Lambda UDFs for data parsing and conversion. This approach offers a comprehensive means to integrate diverse data streams into Amazon Redshift for subsequent analysis.
As you navigate the ever-evolving landscape of data formats and analytics, we hope this exploration provides valuable guidance to derive meaningful insights from your data streams. We welcome any thoughts or questions in the comments section.
About the Authors
M Mehrtens has been working in distributed systems engineering throughout their career, working as a Software Engineer, Architect, and Data Engineer. In the past, M has supported and built systems to process terrabytes of streaming data at low latency, run enterprise Machine Learning pipelines, and created systems to share data across teams seamlessly with varying data toolsets and software stacks. At AWS, they are a Sr. Solutions Architect supporting US Federal Financial customers.
Sindhu Achuthan is a Sr. Solutions Architect with Federal Financials at AWS. She works with customers to provide architectural guidance on analytics solutions using AWS Glue, Amazon EMR, Amazon Kinesis, and other services. Outside of work, she loves DIYs, to go on long trails, and yoga.
Every day across the Amazon Web Services (AWS) cloud infrastructure, we detect and successfully thwart hundreds of cyberattacks that might otherwise be disruptive and costly. These important but mostly unseen victories are achieved with a global network of sensors and an associated set of disruption tools. Using these capabilities, we make it more difficult and expensive for cyberattacks to be carried out against our network, our infrastructure, and our customers. But we also help make the internet as a whole a safer place by working with other responsible providers to take action against threat actors operating within their infrastructure. Turning our global-scale threat intelligence into swift action is just one of the many steps that we take as part of our commitment to security as our top priority. Although this is a never-ending endeavor and our capabilities are constantly improving, we’ve reached a point where we believe customers and other stakeholders can benefit from learning more about what we’re doing today, and where we want to go in the future.
Global-scale threat intelligence using the AWS Cloud
With the largest public network footprint of any cloud provider, our scale at AWS gives us unparalleled insight into certain activities on the internet, in real time. Some years ago, leveraging that scale, AWS Principal Security Engineer Nima Sharifi Mehr started looking for novel approaches for gathering intelligence to counter threats. Our teams began building an internal suite of tools, given the moniker MadPot, and before long, Amazon security researchers were successfully finding, studying, and stopping thousands of digital threats that might have affected its customers.
MadPot was built to accomplish two things: first, discover and monitor threat activities and second, disrupt harmful activities whenever possible to protect AWS customers and others. MadPot has grown to become a sophisticated system of monitoring sensors and automated response capabilities. The sensors observe more than 100 million potential threat interactions and probes every day around the world, with approximately 500,000 of those observed activities advancing to the point where they can be classified as malicious. That enormous amount of threat intelligence data is ingested, correlated, and analyzed to deliver actionable insights about potentially harmful activity happening across the internet. The response capabilities automatically protect the AWS network from identified threats, and generate outbound communications to other companies whose infrastructure is being used for malicious activities.
Systems of this sort are known as honeypots—decoys set up to capture threat actor behavior—and have long served as valuable observation and threat intelligence tools. However, the approach we take through MadPot produces unique insights resulting from our scale at AWS and the automation behind the system. To attract threat actors whose behaviors we can then observe and act on, we designed the system so that it looks like it’s composed of a huge number of plausible innocent targets. Mimicking real systems in a controlled and safe environment provides observations and insights that we can often immediately use to help stop harmful activity and help protect customers.
Of course, threat actors know that systems like this are in place, so they frequently change their techniques—and so do we. We invest heavily in making sure that MadPot constantly changes and evolves its behavior, continuing to have visibility into activities that reveal the tactics, techniques, and procedures (TTPs) of threat actors. We put this intelligence to use quickly in AWS tools, such as AWS Shield and AWS WAF, so that many threats are mitigated early by initiating automated responses. When appropriate, we also provide the threat data to customers through Amazon GuardDuty so that their own tooling and automation can respond.
Three minutes to exploit attempt, no time to waste
Within approximately 90 seconds of launching a new sensor within our MadPot simulated workload, we can observe that the workload has been discovered by probes scanning the internet. From there, it takes only three minutes on average before attempts are made to penetrate and exploit it. This is an astonishingly short amount of time, considering that these workloads aren’t advertised or part of other visible systems that would be obvious to threat actors. This clearly demonstrates the voracity of scanning taking place and the high degree of automation that threat actors employ to find their next target.
As these attempts run their course, the MadPot system analyzes the telemetry, code, attempted network connections, and other key data points of the threat actor’s behavior. This information becomes even more valuable as we aggregate threat actor activities to generate a more complete picture of available intelligence.
Disrupting attacks to maintain business as usual
In-depth threat intelligence analysis also happens in MadPot. The system launches the malware it captures in a sandboxed environment, connects information from disparate techniques into threat patterns, and more. When the gathered signals provide high enough confidence in a finding, the system acts to disrupt threats whenever possible, such as disconnecting a threat actor’s resources from the AWS network. Or, it could entail preparing that information to be shared with the wider community, such as a computer emergency response team (CERT), internet service provider (ISP), a domain registrar, or government agency so that they can help disrupt the identified threat.
As a major internet presence, AWS takes on the responsibility to help and collaborate with the security community when possible. Information sharing within the security community is a long-standing tradition and an area where we’ve been an active participant for years.
In the first quarter of 2023:
We used 5.5B signals from our internet threat sensors and 1.5B signals from our active network probes in our anti-botnet security efforts.
We stopped over 1.3M outbound botnet-driven DDoS attacks.
We shared our security intelligence findings, including nearly a thousand botnet C2 hosts, with relevant hosting providers and domain registrars.
We traced back and worked with external parties to dismantle the sources of 230k L7/HTTP(S) DDoS attacks.
Three examples of MadPot’s effectiveness: Botnets, Sandworm, and Volt Typhoon
Recently, MadPot detected, collected, and analyzed suspicious signals that uncovered a distributed denial of service (DDoS) botnet that was using the domain free.bigbots.[tld] (the top-level domain is omitted) as a command and control (C2) domain. A botnet is made up of compromised systems that belong to innocent parties—such as computers, home routers, and Internet of Things (IoT) devices—that have been previously compromised, with malware installed that awaits commands to flood a target with network packets. Bots under this C2 domain were launching 15–20 DDoS attacks per hour at a rate of about 800 million packets per second.
As MadPot mapped out this threat, our intelligence revealed a list of IP addresses used by the C2 servers corresponding to an extremely high number of requests from the bots. Our systems blocked those IP addresses from access to AWS networks so that a compromised customer compute node on AWS couldn’t participate in the attacks. AWS automation then used the intelligence gathered to contact the company that was hosting the C2 systems and the registrar responsible for the DNS name. The company whose infrastructure was hosting the C2s took them offline in less than 48 hours, and the domain registrar decommissioned the DNS name in less than 72 hours. Without the ability to control DNS records, the threat actor could not easily resuscitate the network by moving the C2s to a different network location. In less than three days, this widely distributed malware and the C2 infrastructure required to operate it was rendered inoperable, and the DDoS attacks impacting systems throughout the internet ground to a halt.
MadPot is effective in detecting and understanding the threat actors that target many different kinds of infrastructure, not just cloud infrastructure, including the malware, ports, and techniques that they may be using. Thus, through MadPot we identified the threat group called Sandworm—the cluster associated with Cyclops Blink, a piece of malware used to manage a botnet of compromised routers. Sandworm was attempting to exploit a vulnerability affecting WatchGuard network security appliances. With close investigation of the payload, we identified not only IP addresses but also other unique attributes associated with the Sandworm threat that were involved in an attempted compromise of an AWS customer. MadPot’s unique ability to mimic a variety of services and engage in high levels of interaction helped us capture additional details about Sandworm campaigns, such as services that the actor was targeting and post-exploitation commands initiated by that actor. Using this intelligence, we notified the customer, who promptly acted to mitigate the vulnerability. Without this swift action, the actor might have been able to gain a foothold in the customer’s network and gain access to other organizations that the customer served.
For our final example, the MadPot system was used to help government cyber and law enforcement authorities identify and ultimately disrupt Volt Typhoon, the widely-reported state-sponsored threat actor that focused on stealthy and targeted cyber espionage campaigns against critical infrastructure organizations. Through our investigation inside MadPot, we identified a payload submitted by the threat actor that contained a unique signature, which allowed identification and attribution of activities by Volt Typhoon that would otherwise appear to be unrelated. By using the data lake that stores a complete history of MadPot interactions, we were able to search years of data very quickly and ultimately identify other examples of this unique signature, which was being sent in payloads to MadPot as far back as August 2021. The previous request was seemingly benign in nature, so we believed that it was associated with a reconnaissance tool. We were then able to identify other IP addresses that the threat actor was using in recent months. We shared our findings with government authorities, and those hard-to-make connections helped inform the research and conclusions of the Cybersecurity and Infrastructure Security Agency (CISA) of the U.S. government. Our work and the work of other cooperating parties resulted in their May 2023 Cybersecurity advisory. To this day, we continue to observe the actor probing U.S. network infrastructure, and we continue to share details with appropriate government cyber and law enforcement organizations.
Putting global-scale threat intelligence to work for AWS customers and beyond
At AWS, security is our top priority, and we work hard to help prevent security issues from causing disruption to your business. As we work to defend our infrastructure and your data, we use our global-scale insights to gather a high volume of security intelligence—at scale and in real time—to help protect you automatically. Whenever possible, AWS Security and its systems disrupt threats where that action will be most impactful; often, this work happens largely behind the scenes. As demonstrated in the botnet case described earlier, we neutralize threats by using our global-scale threat intelligence and by collaborating with entities that are directly impacted by malicious activities. We incorporate findings from MadPot into AWS security tools, including preventative services, such as AWS WAF, AWS Shield, AWS Network Firewall, and Amazon Route 53 Resolver DNS Firewall, and detective and reactive services, such as Amazon GuardDuty, AWS Security Hub, and Amazon Inspector, putting security intelligence when appropriate directly into the hands of our customers, so that they can build their own response procedures and automations.
But our work extends security protections and improvements far beyond the bounds of AWS itself. We work closely with the security community and collaborating businesses around the world to isolate and take down threat actors. In the first half of this year, we shared intelligence of nearly 2,000 botnet C2 hosts with relevant hosting providers and domain registrars to take down the botnets’ control infrastructure. We also traced back and worked with external parties to dismantle the sources of approximately 230,000 Layer 7 DDoS attacks. The effectiveness of our mitigation strategies relies heavily on our ability to quickly capture, analyze, and act on threat intelligence. By taking these steps, AWS is going beyond just typical DDoS defense, and moving our protection beyond our borders.
We’re glad to be able to share information about MadPot and some of the capabilities that we’re operating today. For more information, see this presentation from our most recent re:Inforce conference: How AWS threat intelligence becomes managed firewall rules, as well as an overview post published today, Meet MadPot, a threat intelligence tool Amazon uses to protect customers from cybercrime, which includes some good information about the AWS security engineer behind the original creation of MadPot. Going forward, you can expect to hear more from us as we develop and enhance our threat intelligence and response systems, making both AWS and the internet as a whole a safer place.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
This post is a continuation of a two-part series. In the first part, we delved into Apache Flink‘s internal mechanisms for checkpointing, in-flight data buffering, and handling backpressure. We covered these concepts in order to understand how buffer debloating and unaligned checkpoints allow us to enhance performance for specific conditions in Apache Flink applications.
In Part 1, we introduced and examined how to use buffer debloating to improve in-flight data processing. In this post, we focus on unaligned checkpoints. This feature has been available since Apache Flink 1.11 and has received many improvements since then. Unaligned checkpoints help, under specific conditions, to reduce checkpointing time for applications suffering temporary backpressure, and can be now enabled in Amazon Managed Service for Apache Flink applications running Apache Flink 1.15.2 through a support ticket.
Even though this feature might improve performance for your checkpoints, if your application is constantly failing because of checkpoints timing out, or is suffering from having constant backpressure, you may require a deeper analysis and redesign of your application.
Aligned checkpoints
As discussed in Part 1, Apache Flink checkpointing allows applications to record state in case of failure. We’ve already discussed how checkpoints, when triggered by the job manager, signal all source operators to snapshot their state, which is then broadcasted as a special record called a checkpoint barrier. This process achieves exactly-once consistency for state in a distributed streaming application through the alignment of these barriers.
Let’s walk through the process of aligned checkpoints in a standard Apache Flink application. Remember that Apache Flink distributes the workload horizontally: each operator (a node in the logical flow of your application, including sources and sinks) is split into multiple sub-tasks based on its parallelism.
Barrier alignment
The alignment of checkpoint barriers is crucial for achieving exactly-once consistency in Apache Flink applications during checkpoint runs. To recap, when a job manager triggers a checkpoint, all sub-tasks of source operators receive a signal to initiate the checkpoint process. Each sub-task independently snapshots its state to the state backend and broadcasts a special record known as a checkpoint barrier to all outgoing streams.
When an application operates with a parallelism higher than 1, multiple instances of each task—referred to as sub-tasks—enable parallel message consumption and processing. A sub-task can receive distinct partitions of the same stream from different upstream sub-tasks, such as after a stream repartitioning with keyBy or rebalance operations. To maintain exactly-once consistency, all sub-tasks must wait for the arrival of all checkpoint barriers before taking a snapshot of the state. The following diagram illustrates the checkpoint barriers flow.
This phase is called checkpoint alignment. During alignment, the sub-task stops processing records from the partitions from which it has already received barriers, as shown in the following figure.
However, it continues to process partitions that are behind the barrier.
When barriers from all upstream partitions have arrived, the sub-task takes a snapshot of its state.
Then it broadcasts the barrier downstream.
The time a sub-task spends waiting for all barriers to arrive is measured by the checkpoint Alignment Duration metric, which can be observed in the Apache Flink UI.
If the application experiences backpressure, an increase in this metric could lead to longer checkpoint durations and even checkpoint failures due to timeouts. This is where unaligned checkpoints become a viable option to potentially enhance checkpointing performance.
Unaligned checkpoints
Unaligned checkpoints address situations where backpressure is not just a temporary spike, but results in timeouts for aligned checkpoints, due to barrier queuing within the stream. As discussed in Part 1, checkpoint barriers can’t overtake regular records. Therefore, significant backpressure can slow down the movement of barriers across the application, potentially causing checkpoint timeouts.
The objective of unaligned checkpoints is to enable barrier overtaking, allowing barriers to move swiftly from source to sink even when the data flow is slower than anticipated.
Building on what we saw in Part 1 concerning checkpoints and what aligned checkpoints are, let’s explore how unaligned checkpoints modify the checkpointing mechanism.
Upon emission, each source’s checkpoint barrier is injected into the stream flowing across sub-tasks. It travels from the source output network buffer queue into the input network buffer queue of the subsequent operator.
Upon the arrival of the first barrier in the input network buffer queue, the operator initially waits for barrier alignment. If the specified alignment timeout expires because not all barriers have reached the end of the input network buffer queue, the operator switches to unaligned checkpoint mode.
The alignment timeout can be set programmatically by env.getCheckpointConfig().setAlignedCheckpointTimeout(Duration.ofSeconds(30)), but modifying the default is not recommended in Apache Flink 1.15.
The operator waits until all checkpoint barriers are present in the input network buffer queue before triggering the checkpoint. Unlike aligned checkpoints, the operator doesn’t need to wait for all barriers to reach the queue’s end, allowing the operator to have in-flight data from the buffer that hasn’t been processed before checkpoint initiation.
After all barriers have arrived in the input network buffer queue, the operator advances the barrier to the end of the output network buffer queue. This enhances checkpointing speed because the barrier can smoothly traverse the application from source to sink, independent of the application’s end-to-end latency.
After forwarding the barrier to the output network buffer queue, the operator initiates the snapshot of in-flight data between the barriers in the input and output network buffer queues, along with the snapshot of the state.
Although processing is momentarily paused during this process, the actual writing to the remote persistent state storage occurs asynchronously, preventing potential bottlenecks.
The local snapshot, encompassing in-flight messages and state, is saved asynchronously in the remote persistent state store, while the barrier continues its journey through the application.
When to use unaligned checkpoints
Remember, barrier alignment only occurs between partitions coming from different sub-tasks of the same operator. Therefore, if an operator is experiencing temporary backpressure, enabling unaligned checkpoints may be beneficial. This way, the application doesn’t have to wait for all barriers to reach the operator before performing the snapshot of state or moving the barrier forward.
Temporary backpressure could arise from the following:
A surge in data ingestion
Backfilling or catching up with historical data
Increased message processing time due to delayed external systems
Another scenario where unaligned checkpoints prove advantageous is when working with exactly-once sinks. Utilizing the two-phase commit sink function for exactly-once sinks, unaligned checkpoints can expedite checkpoint runs, thereby reducing end-to-end latency.
When not to use unaligned checkpoints
Unaligned checkpoints won’t reduce the time required for savepoints (called snapshots in the Amazon Managed Service for Apache Flink implementation) because savepoints exclusively utilize aligned checkpoints. Furthermore, because Apache Flink doesn’t permit concurrent unaligned checkpoints, savepoints won’t occur simultaneously with unaligned checkpoints, potentially elongating savepoint durations.
Unaligned checkpoints won’t fix any underlying issue in your application design. If your application is suffering from persistent backpressure or constant checkpointing timeouts, this might indicate data skewness or underprovisioning, which may require improving and tuning the application.
Using unaligned checkpoints with buffer debloating
One alternative for reducing the risks associated with an increased state size is to combine unaligned checkpoints with buffer debloating. This approach results in having less in-flight data to snapshot and store in the state, along with less data to be used for recovery in case of failure. This synergy facilitates enhanced performance and efficient checkpoint runs, leading to smaller checkpointing sizes and faster recovery times. When testing the use of unaligned checkpoints, we recommend doing so with buffer debloating to prevent the state size from increasing.
Limitations
Unaligned checkpoints are subject to the following limitations:
They provide no benefit for operators with a parallelism of 1.
They only improve performance for operators where barrier alignment would have occurred. This alignment happens only if records are coming from different sub-tasks of the same operator, for example, through repartitioning or keyBy operations.
Operators receiving input from multiple sources or participating in joins might not experience improvements, because the operator would be receiving data from different operators in those cases.
Although checkpoint barriers can surpass records in the network’s buffer queue, this won’t occur if the sub-task is currently processing a message. If processing a message takes too much time (for example, a flat-map operation emitting numerous records for each input record), barrier handling will be delayed.
As we have seen, savepoints always use aligned checkpoints. If the savepoints of your applications are slow due to barrier alignment, unaligned checkpoints will not help.
Additional limitations affect watermarks, message ordering, and broadcast state in recovery. For more details, refer to Limitations.
Considerations
Considerations for implementing unaligned checkpoints:
Unaligned checkpoints introduce additional I/O to checkpoint storage
Checkpoints encompass not only operator state but also in-flight data within network buffer queues, leading to increased state size
Recommendations
We offer the following recommendations:
Consider enabling unaligned checkpoints only if both of the following conditions are true:
Checkpoints are timing out.
The average checkpoint Async Duration of any operator is more than 50% of the total checkpoint duration for the operator (sum of Sync Duration + Async Duration).
Consider enabling buffer debloating first, and evaluate whether it solves the problem of checkpoints timing out.
If buffer debloating doesn’t help, consider enabling unaligned checkpoints along with buffer debloating. Buffer debloating mitigates the drawbacks of unaligned checkpoints, reducing the amount of in-flight data.
If unaligned checkpoints and buffer debloating together don’t improve checkpoint alignment duration, consider testing unaligned checkpoints alone.
Finally, but most importantly, always test unaligned checkpoints in a non-production environment first, running some comparative performance testing with a realistic workload, and verify that unaligned checkpoints actually reduce checkpoint duration.
Conclusion
This two-part series explored advanced strategies for optimizing checkpointing within your Amazon Managed Service for Apache Flink applications. By harnessing the potential of buffer debloating and unaligned checkpoints, you can unlock significant performance improvements and streamline checkpoint processes. However, it’s important to understand when these techniques will provide improvements and when they will not. If you believe your application may benefit from checkpoint performance improvement, you can enable these features in your Amazon Managed Service For Apache Flink version 1.15 applications. We recommend first enabling buffer debloating and testing the application. If you are still not seeing the expected outcome, enable buffer debloating with unaligned checkpoints. This way, you can immediately reduce the state size and the additional I/O to state backends. Lastly, you may try using unaligned checkpoints by itself, bearing in mind the considerations we’ve mentioned.
With a deeper understanding of these techniques and their applicability, you are better equipped to maximize the efficiency of checkpoints and mitigate the effect of backpressure in your Apache Flink application.
About the Authors
Lorenzo Nicora works as Senior Streaming Solution Architect helping customers across EMEA. He has been building cloud-native, data-intensive systems for over 25 years, working in the finance industry both through consultancies and for FinTech product companies. He has leveraged open-source technologies extensively and contributed to several projects, including Apache Flink.
Francisco Morillo is a Streaming Solutions Architect at AWS. Francisco works with AWS customers helping them design real-time analytics architectures using AWS services, supporting Amazon Managed Streaming for Apache Kafka (Amazon MSK) and AWS’s managed offering for Apache Flink.
This post is the first of a two-part series regarding checkpointing mechanisms and in-flight data buffering. In this first part, we explain some of the fundamental Apache Flink internals and cover the buffer debloating feature. In the second part, we focus on unaligned checkpoints.
Apache Flink is an open-source distributed engine for stateful processing over unbounded datasets (streams) and bounded datasets (batches). Amazon Managed Service for Apache Flink, formerly known as Amazon Kinesis Data Analytics, is the AWS service offering fully managed Apache Flink.
Apache Flink is designed for stateful processing at scale, for high throughput and low latency. It scales horizontally, distributing processing and state across multiple nodes, and is designed to withstand failures without compromising the exactly-once consistency it provides.
Internally, Apache Flink uses clever mechanisms to maintain exactly-once state consistency, while also optimizing for throughput and reduced latency. The default behavior works well for most use cases. Recent versions introduced two functionalities that can be optionally enabled to improve application performance under particular conditions: buffer debloating and unaligned checkpoints.
To understand how these functionalities can help and when to use them, we need to dive deep into some of the fundamental internal mechanisms of Apache Flink: checkpointing, in-flight data buffering, and backpressure.
Maintaining state consistency through failures with checkpointing
Apache Flink checkpointing periodically saves the internal application state for recovering in case of failure. Each of the distributed components of an application asynchronously snapshots its state to an external persistent datastore. The challenge is taking snapshots guaranteeing exactly-once consistency. A naïve “stop-the-world, take a snapshot” implementation would never meet the high throughput and low latency goals Apache Flink has been designed for.
Let’s walk through the process of checkpointing in a simple streaming application.
As shown in the following figure, Apache Flink distributes the work horizontally. Each operator (a node in the logical flow of your application, including sources and sinks) is split into multiple sub-tasks, based on its parallelism. The application is coordinated by a job manager. Checkpoints are periodically initiated by the job manager, sending a signal to all source operators’ sub-tasks.
On receiving the signal, each source sub-task independently snapshots its state (for example, the offsets of the Kafka topic it is consuming) to a persistent storage, and then broadcasts a special record called checkpoint barrier (“CB” in the following diagrams) to all outgoing streams. Checkpoint barriers work similarly to watermarks in Apache Flink, flowing in-bands, along with normal records. A barrier does not overtake normal records and is not overtaken.
When a downstream operator’s sub-task receives all checkpoint barriers from all input channels, it starts snapshotting its state.
A sub-task does not pause processing while saving its state to the remote, persistent state backend. This is a two-phase operation. First, the sub-task takes a snapshot of the state, on the local file system or in memory, depending on application configuration. This operation is blocking but very fast. When the snapshot is complete, it restarts processing records, while the state is asynchronously saved to the external, persistent state store. When the state is successfully saved to the state store, the sub-task acknowledges to the job manager that its checkpointing is complete.
The time a sub-task spends on the synchronous and asynchronous parts of the checkpoint is measured by Sync Duration and Async Duration metrics, shown by the Apache Flink UI. It is then asynchronously sent to the backend. After the fast snapshot, the sub-task restarts processing messages. The backend notifies the sub-task when the state has been successfully saved. The sub-task, in turn, sends an acknowledgment to the job manager that checkpointing is complete.
Checkpoint barriers propagate through all operators, down to the sinks. When all sink sub-tasks have acknowledged the checkpoint to the job manager, the checkpoint is declared complete and can be used to recover the application, for example in case of failure.
Checkpoint barrier alignment
A sub-task may receive different partitions of the same stream from different upstream sub-tasks, for example when a stream is repartitioned with a keyBy or a rebalance. Each upstream sub-task will emit a checkpoint barrier independently. To maintain exactly-once consistency, the sub-task must wait for the barriers to arrive on all input partitions before taking a snapshot of its state.
This phase is called checkpoint alignment. During the alignment, the sub-task stops processing records from the partitions it already received the barrier from and continues processing the partitions that are behind the barrier.
After the barriers from all upstream partitions have arrived, the sub-task takes the snapshot of its state and then broadcasts the barrier downstream.
The time spent by a sub-task while aligning barriers is measured by the Checkpoint Alignment Duration metric, shown by the Apache Flink UI.
In-flight data buffering
To optimize for throughput, Apache Flink tries to keep each sub-task always busy. This is achieved by transmitting records over the network in blocks and by buffering in-flight data. Note that this is data transmission optimization; Flink operators always process records one at the time.
Data is handed over between sub-tasks in units called network buffers. A network buffer has a fixed size, in bytes.
Sub-tasks also buffer in-flight input and output data. These buffers are called network buffer queues. Each queue is composed of multiple network buffers. Each sub-task has an input network buffer queue for each upstream sub-task and an output network buffer queue for each downstream sub-task.
Each record emitted by the sub-task is serialized, put into network buffers, and published to the output network buffer queue. To use all the available space, multiple messages can be packed into a single network buffer or split across subsequent network buffers.
A separate thread sends full network buffers over the network, where they are stored in the destination sub-task’s input network buffer queue.
When the destination sub-task thread is free, it deserializes the network buffers, rebuilds the records, and processes them one at a time.
Backpressure
If a sub-task can’t keep up with processing records at the same pace they are received, the input queue fills up. When the input queue is full, the upstream sub-task stops sending data.
Data accumulates in the sender’s output queue. When this is also full, the sender sub-task stops processing records, accumulating received data in its own input queue, and the effects propagates upstream.
This is the backpressure that Apache Flink uses to control the internal flow, preventing slow operators from being overwhelmed by slowing down the upstream flow. Backpressure is a safety mechanism to maximize the application throughput. It can be temporary, in case of an unexpected peak of ingested data, for example. If not temporary, it is usually the symptom—not the cause—that the application is not designed correctly or it has insufficient resources to process the workload.
In-flight buffering and checkpoint barriers
As checkpoint barriers flow with normal records, they also flow in the network buffers, through the input and output queues. In normal conditions, barriers don’t overtake records, and they are never overtaken. If records are queueing up due to backpressure, checkpoint barriers are also stuck in the queue, taking longer time to propagate from the sources to the sinks, delaying the completion of the checkpoint.
In the second part of this series, we will see how unaligned checkpoints can let barriers overtake records under specific conditions. For now, let’s see how we can optimize the size of input and output queues with buffer debloating.
Buffer debloating to optimize in-flight data
The default network buffer queue size is a good compromise for most applications. You can modify this size, but it applies to all sub-tasks, and it may be difficult to optimize this one-size-fits-all across different operators.
Longer queues support bigger throughout, but they may slow down checkpoint barriers that have to go through longer queues, causing longer End to End Checkpoint Duration. Ideally, the amount of in-flight data should be adjusted based on the actual throughput.
In version 1.14, Apache Flink introduced buffer debloating, which can be enabled to adjust in-flight data of each sub-task, based on the current throughput the sub-task is processing, and periodically reassess and readjust it.
How buffer debloating helps your application
Consider a streaming application, ingesting records from a streaming source and publishing the results to a streaming destination after some transformations. Under normal conditions, the application is sized to process the incoming throughput smoothly. Our destination has limited capacity, for example a Kafka topic throttled via quotas, sufficient to handle the normal throughput, with some margin.
Imagine that the ingestion throughput has occasional peaks. These peaks exceed the limits of the streaming destination (throughput quota of the Kafka topic), which starts throttling.
Because the sink can’t process the full throughput, in-flight data accumulates upstream of the sink, causing backpressure on the upstream operator. The effect eventually propagates up to the source, and the source starts lagging behind the most recent record in the source stream.
As long this is a temporary condition, backpressure and lagging are not a problem per se, as long as the application is able to catch up when the peak has finished.
Unfortunately, accumulating in-flight data also slows down the propagation of the checkpoint barriers. Checkpoint End to End Duration goes up, and checkpoints may eventually time out.
The situation is even worse if the sink uses two-phase commit for exactly-once guarantees. For example, KafkaSink uses Kafka transactions committed on checkpoints. If checkpoints become too slow, transactions are committed later, significantly increasing the latency of any downstream consumer using a read-committed isolation level.
Slow checkpoints under backpressure may also cause a vicious cycle. A slowed-down application eventually crashes, and recovers from the last checkpoint that is quite old. This causes a long reprocessing that, in turn, induces more backpressure and even slower checkpoints.
In this case, buffer debloating can help by adjusting the amount of in-flight data based on the throughput each sub-task is actually processing. When a sub-task is throttled by backpressure, the amount of in-flight data is reduced, also reducing the time checkpoint barriers take to go through all operators. Checkpoint End to End Duration goes down, and checkpoints do not time out.
Buffer debloating internals
Buffer debloating estimates the throughput a sub-task is capable of processing, assuming no idling, and limits the upstream in-flight data buffers to contain just enough data to be processed in 1 second (by default).
For efficiency, network buffers in the queues are fixed. Buffer debloating caps the usable size of each network buffer, making it smaller when the sub-task is processing slowly.
The benefits of less in-flight data depends on whether Apache Flink is using standard checkpoint alignment, the default behavior described so far, or unaligned checkpoints. We will examine unaligned checkpoints in the second part of this series, but let’s see the effect of buffer debloating, briefly.
With aligned checkpoints (default behavior) – Less in-flight data makes checkpoint barrier propagation faster, ultimately reducing the end-to-end checkpoint duration but also making it more predictable
With unaligned checkpoints (optional) – Less in-flight data reduces the amount of in-flight records stored with the checkpoint, ultimately reducing the checkpoint size
What buffer debloating does not do
Note that the problem we are trying to solve is slow checkpointing (or excessive checkpointing size, with unaligned checkpoints). Buffer debloating helps making checkpointing faster.
Buffer debloating does not remove backpressure. Backpressure is the internal protective mechanism that Apache Flink uses when some part of the application is not able to cope with the incoming throughput. To reduce backpressure, you have to work on other aspects of the application. When backpressure is only temporary, for example under peak conditions, the only way of removing it would be sizing the end-to-end system for the peak, rather than normal workload. But this could be impossible or too expensive.
Buffer debloating helps reduce and keep checkpoint duration stable under exceptional and temporary conditions. If an application experiences backpressure under its normal workload, or checkpoints are too slow under normal conditions, you should investigate the implementation of your application to understand the root cause.
When the automatic throughput prediction fails
Buffer debloating doesn’t have any particular drawback, but in corner cases, the mechanism may incorrectly estimate the throughput, and the resulting amount of in-flight data may not be optimal.
Estimating the throughput is complex when an operator receives data from multiple upstream operators, connected streams or unions, with very different throughput. It may also take time to adjust to a sudden spike, causing a temporary suboptimal buffering.
Too small in-flight data may reduce the throughput the sub-task can process (it will be idling), causing more backpressure upstream
Too large buffers may slow down checkpointing and increase the checkpoint size (with unaligned checkpoints)
Conclusion
The checkpointing mechanism makes Apache Flink fault tolerant, providing exactly-once state consistency. In-flight data buffering and backpressure control the data flow within the distributed streaming application maximize the throughput. Apache Flink default behaviors and configurations are good for most workloads.
The effectiveness of buffer debloating depends on the characteristics of the workload and the application. The general recommendation is to test the functionality in a non-production environment with a realistic workload to verify it actually helps with your use case.
Under particular conditions, the combined effect of backpressure and in-flight data buffering may slow down checkpointing, increase checkpointing size (with unaligned checkpoints), and even cause checkpoints to fail. In these cases, enabling unaligned checkpointing may help reduce checkpoint duration or size.
In the second part of this series, we will understand better unaligned checkpoints and how they can help your application checkpointing efficiently in presence of backpressure, especially in combination with buffer debloating.
About the Authors
Lorenzo Nicora works as Senior Streaming Solution Architect at AWS, helping customers across EMEA. He has been building cloud-native, data-intensive systems for over 25 years, working in the finance industry both through consultancies and for FinTech product companies. He has leveraged open-source technologies extensively and contributed to several projects, including Apache Flink.
Francisco Morillo is a Streaming Solutions Architect at AWS. Francisco works with AWS customers helping them design real-time analytics architectures using AWS services, supporting Amazon Managed Streaming for Apache Kafka (Amazon MSK) and AWS’s managed offering for Apache Flink.
In-memory databases play a critical role in modern computing, particularly in reducing the strain on existing resources, scaling workloads efficiently, and minimizing the cost of infrastructure. The advanced performance capabilities of in-memory databases make them vital for demanding applications characterized by voluminous data, real-time analytics, and rapid response requirements.
In this edition of Let’s Architect!, we are introducing caching strategies and, further, examining case studies that use Amazon Web Services (AWS), like Amazon ElastiCache or Amazon MemoryDB for Redis, in real workloads where customers share the reasoning behind their approaches. It is very important understanding the context for leveraging a specific solution or pattern, and many common questions can be answered with these resources.
Many services built at Amazon rely on caching systems in the background to speed up performance, deal with low latency requirements, and avoid overloading on source databases and other microservices. Operating caches and adding caches into our systems may present complex challenges in terms of monitoring, data consistency, and load on the other components of the system. Indeed, a cache can give big benefits, but it’s also a new component to run and keep healthy. Furthermore, engineers may need to use empirical methods to choose the cache size, expiration policy, and eviction policy: we always have to perform tests and use the metrics to tune the setup.
With this Amazon Builder’s Library resource, you can learn strategies for using caching in your architecture and best practices directly from Amazon’s engineers.
Discover how Yahoo effectively leverages the power of Amazon ElastiCache and data tiering to process an astounding 1.3 million advertising data events per second, all while generating savings of up to 50% on their overall bill.
Data tiering is an ingenious method to scale up to hundreds of terabytes of capacity by intelligently managing data. It achieves this by automatically shifting the least-recently accessed data between RAM and high-performance SSDs.
In this video, you will gain insights into how data tiering operates and how you can unlock ultra-fast speeds and seamless scalability for your workloads in a cost-efficient manner. Furthermore, you can also learn how it’s implemented under the hood.
MemoryDB is a robust, durable database marked by microsecond reads, low single-digit millisecond writes, scalability, and fortified enterprise security. It guarantees an impressive 99.99% availability, coupled with instantaneous recovery without any data loss.
In this session, we explore multiple use cases across sectors, such as Financial Services, Retail, and Media & Entertainment, like payment processing, message brokering, and durable session store applications. Moreover, through a practical demonstration, you can learn how to utilize MemoryDB to establish a microservices message broker for a Media & Entertainment application.
MemoryDB offers the kind of ultra-fast performance that only an in-memory database can deliver, curtailing latency to microseconds and processing 160+ million requests per second —without data loss. In this re:Invent 2022 session, you will understand why Samsung SmartThings selected MemoryDB as the engine to power the next generation of their IoT device connectivity platform, one that processes millions of events every day.
You can also discover the intricate design of MemoryDB and how it ensures data durability without compromising the performance of in-memory operations, thanks to the utilization of a multi-AZ transactional log. This session is an enlightening deep-dive into durable, in-memory data operations.
In this edition of AWS Online Tech Talks, explore Amazon ElastiCache, a managed service that facilitates the seamless setup, operation, and scaling of widely used, open-source–compatible, in-memory datastores in the cloud environment. This service positions you to develop data-intensive applications or enhance the performance of your existing databases through high-throughput, low-latency, in-memory datastores. Learn how it is leveraged for caching, session stores, gaming, geospatial services, real-time analytics, and queuing functionalities.
This course can help cultivate a deeper understanding of Amazon ElastiCache, and how it can be used to accelerate your data processing while maintaining robustness and reliability.
Customers often need to architect solutions to support components across multiple cloud service providers, a need which may arise if they have acquired a company running on another cloud, or for functional purposes where specific services provide a differentiated capability. In this post, we will show you how to use the AWS Cloud Development Kit (AWS CDK) to create a single pane of glass for managing your multicloud resources.
AWS CDK is an open source framework that builds on the underlying functionality provided by AWS CloudFormation. It allows developers to define cloud resources using common programming languages and an abstraction model based on reusable components called constructs. There is a misconception that CloudFormation and CDK can only be used to provision resources on AWS, but this is not the case. The CloudFormation registry, with support for third party resource types, along with custom resource providers, allow for any resource that can be configured via an API to be created and managed, regardless of where it is located.
Multicloud solution design paradigm
Multicloud solutions are often designed with services grouped and separated by cloud, creating a segregation of resource and functions within the design. This approach leads to a duplication of layers of the solution, most commonly a duplication of resources and the deployment processes for each environment. This duplication increases cost, and leads to a complexity of management increasing the potential break points within the solution or practice.
Along with simplifying resource deployments, and the ever-increasing complexity of customer needs, so too has the need increased for the capability of IaC solutions to deploy resources across hybrid or multicloud environments. Through meeting this need, a proliferation of supported tools, frameworks, languages, and practices has created “choice overload”. At worst, this scares the non-cloud-savvy away from adopting an IaC solution benefiting their cloud journey, and at best confuses the very reason for adopting an IaC practice.
A single pane of glass
Systems Thinking is a holistic approach that focuses on the way a system’s constituent parts interrelate and how systems work as a whole especially over time and within the context of larger systems. Systems thinking is commonly accepted as the backbone of a successful systems engineering approach. Designing solutions taking a full systems view, based on the component’s function and interrelation within the system across environments, more closely aligns with the ability to handle the deployment of each cloud-specific resource, from a single control plane.
While AWS provides a list of services that can be used to help design, manage and operate hybrid and multicloud solutions, with AWS as the primary cloud you can go beyond just using services to support multicloud. CloudFormation registry resource types model and provision resources using custom logic, as a component of stacks in CloudFormation. Public extensions are not only provided by AWS, but third-party extensions are made available for general use by publishers other than AWS, meaning customers can create their own extensions and publish them for anyone to use.
The AWS CDK, which has a 1:1 mapping of all AWS CloudFormation resources, as well as a library of abstracted constructs, supports the ability to import custom AWS CloudFormation extensions, enabling customers and partners to create custom AWS CDK constructs for their extensions. The chosen programming language can be used to inherit and abstract the custom resource into reusable AWS CDK constructs, allowing developers to create solutions that contain native AWS extensions along with secondary hybrid or alternate cloud resources.
Providing the ability to integrate mixed resources in the same stack more closely aligns with the functional design and often diagrammatic depiction of the solution. In essence, we are creating a single IaC pane of glass over the entire solution, deployed through a single control plane. This lowers the complexity and the cost of maintaining separate modules and deployment pipelines across multiple cloud providers.
A common use case for a multicloud: disaster recovery
One of the most common use cases of the requirement for using components across different cloud providers is the need to maintain data sovereignty while designing disaster recovery (DR) into a solution.
Data sovereignty is the idea that data is subject to the laws of where it is physically located, and in some countries extends to regulations that if data is collected from citizens of a geographical area, then the data must reside in servers located in jurisdictions of that geographical area or in countries with a similar scope and rigor in their protection laws.
This requires organizations to remain in compliance with their host country, and in cases such as state government agencies, a stricter scope of within state boundaries, data sovereignty regulations. Unfortunately, not all countries, and especially not all states, have multiple AWS regions to select from when designing where their primary and recovery data backups will reside. Therefore, the DR solution needs to take advantage of multiple cloud providers in the same geography, and as such a solution must be designed to backup or replicate data across providers.
The multicloud solution
A multicloud solution to the proposed use case would be the backup of data from an AWS resource such as an Amazon S3 bucket to another cloud provider within the same geography, such as an Azure Blob Storage container, using AWS event driven behaviour to trigger the copying of data from the primary AWS resource to the secondary Azure backup resource.
Following the IaC single pane of glass approach, the Azure Blob Storage container is created as a resource type in the CloudFormation Registry, and imported into the AWS CDK to be used as a construct in the solution. However, before the extension resource type can be used effectively in the CDK as a reusable construct and added to your private library, you will first need to go through the import into CDK process for creating Constructs.
There are three different levels of constructs, beginning with low-level constructs, which are called CFN Resources (or L1, short for “layer 1”). These constructs directly represent all resources available in AWS CloudFormation. They are named CfnXyz, where Xyz is name of the resource.
Layer 1 Construct
In this example, an L1 construct named CfnAzureBlobStorage represents an Azure::BlobStorage AWS CloudFormation extension. Here you also explicitly configure the ref property, in order for higher level constructs to access the Output value which will be the Azure blob container url being provisioned.
As with every CDK Construct, the constructor arguments are scope, id and props. scope and id are propagated to the cdk.Construct base class. The props argument is of type CfnAzureBlobStorageProps which includes four properties all of type string. This is how the Azure credentials are propagated down from upstream constructs.
Layer 2 Construct
The next level of constructs, L2, also represent AWS resources, but with a higher-level, intent-based API. They provide similar functionality, but incorporate the defaults, boilerplate, and glue logic you’d be writing yourself with a CFN Resource construct. They also provide convenience methods that make it simpler to work with the resource.
In this example, an L2 construct is created to abstract the CfnAzureBlobStorage L1 construct and provides additional properties and methods.
The custom L2 construct class is declared as AzureBlobStorage, this time without the Cfn prefix to represent an L2 construct. This time the constructor arguments include the Azure credentials and client secret, and the ref from the L1 construct us output to the public variable AzureBlobContainerUrl.
As an L2 construct, the AzureBlobStorage construct could be used in CDK Apps along with AWS Resource Constructs in the same Stack, to be provisioned through AWS CloudFormation creating the IaC single pane of glass for a multicloud solution.
Layer 3 Construct
The true value of the CDK construct programming model is in the ability to extend L2 constructs, which represent a single resource, into a composition of multiple constructs that provide a solution for a common task. These are Layer 3, L3, Constructs also known as patterns.
In this example, the L3 construct represents the solution architecture to backup objects uploaded to an Amazon S3 bucket into an Azure Blob Storage container in real-time, using AWS Lambda to process event notifications from Amazon S3.
import { RemovalPolicy, Duration, CfnOutput } from "aws-cdk-lib";
import { Bucket, BlockPublicAccess, EventType } from "aws-cdk-lib/aws-s3";
import { DockerImageFunction, DockerImageCode } from "aws-cdk-lib/aws-lambda";
import { PolicyStatement, Effect } from "aws-cdk-lib/aws-iam";
import { LambdaDestination } from "aws-cdk-lib/aws-s3-notifications";
import { IStringParameter, StringParameter } from "aws-cdk-lib/aws-ssm";
import { Secret, ISecret } from "aws-cdk-lib/aws-secretsmanager";
import { Construct } from "constructs";
import { AzureBlobStorage } from "./azure-blob-storage";

// L3 Construct
export class S3ToAzureBackupService extends Construct {
  constructor(
    scope: Construct,
    id: string,
    azureSubscriptionIdParamName: string,
    azureClientIdParamName: string,
    azureTenantIdParamName: string,
    azureClientSecretName: string
  ) {
    super(scope, id);

    // Retrieve existing SSM Parameters
    const azureSubscriptionIdParameter = this.getSSMParameter("AzureSubscriptionIdParam", azureSubscriptionIdParamName);
    const azureClientIdParameter = this.getSSMParameter("AzureClientIdParam", azureClientIdParamName);
    const azureTenantIdParameter = this.getSSMParameter("AzureTenantIdParam", azureTenantIdParamName);

    // Retrieve existing Azure Client Secret
    const azureClientSecret = this.getSecret("AzureClientSecret", azureClientSecretName);

    // Create an S3 bucket
    const sourceBucket = new Bucket(this, "SourceBucketForAzureBlob", {
      removalPolicy: RemovalPolicy.RETAIN,
      blockPublicAccess: BlockPublicAccess.BLOCK_ALL,
    });

    // Create a corresponding Azure Blob Storage account and a Blob Container
    const azurebBlobStorage = new AzureBlobStorage(
      this,
      "MyCustomAzureBlobStorage",
      azureSubscriptionIdParameter.stringValue,
      azureClientIdParameter.stringValue,
      azureTenantIdParameter.stringValue,
      azureClientSecretName
    );

    // Create a lambda function that will receive notifications from S3 bucket
    // and copy the new uploaded object to Azure Blob Storage
    const copyObjectToAzureLambda = new DockerImageFunction(
      this,
      "CopyObjectsToAzureLambda",
      {
        timeout: Duration.seconds(60),
        code: DockerImageCode.fromImageAsset("copy_s3_fn_code", {
          buildArgs: {
            "--platform": "linux/amd64"
          }
        }),
      },
    );

    // Add an IAM policy statement to allow the Lambda function to access the
    // S3 bucket
    sourceBucket.grantRead(copyObjectToAzureLambda);

    // Add an IAM policy statement to allow the Lambda function to get the contents
    // of an S3 object
    copyObjectToAzureLambda.addToRolePolicy(
      new PolicyStatement({
        effect: Effect.ALLOW,
        actions: ["s3:GetObject"],
        resources: [`arn:aws:s3:::${sourceBucket.bucketName}/*`],
      })
    );

    // Set up an S3 bucket notification to trigger the Lambda function
    // when an object is uploaded
    sourceBucket.addEventNotification(
      EventType.OBJECT_CREATED,
      new LambdaDestination(copyObjectToAzureLambda)
    );

    // Grant the Lambda function read access to existing SSM Parameters
    azureSubscriptionIdParameter.grantRead(copyObjectToAzureLambda);
    azureClientIdParameter.grantRead(copyObjectToAzureLambda);
    azureTenantIdParameter.grantRead(copyObjectToAzureLambda);

    // Put the Azure Blob Container Url into SSM Parameter Store
    this.createStringSSMParameter(
      "AzureBlobContainerUrl",
      "Azure blob container URL",
      "/s3toazurebackupservice/azureblobcontainerurl",
      azurebBlobStorage.blobContainerUrl,
      copyObjectToAzureLambda
    );

    // Grant the Lambda function read access to the secret
    azureClientSecret.grantRead(copyObjectToAzureLambda);

    // Output S3 bucket arn
    new CfnOutput(this, "sourceBucketArn", {
      value: sourceBucket.bucketArn,
      exportName: "sourceBucketArn",
    });

    // Output the Blob Conatiner Url
    new CfnOutput(this, "azureBlobContainerUrl", {
      value: azurebBlobStorage.blobContainerUrl,
      exportName: "azureBlobContainerUrl",
    });
  }

}
The custom L3 construct can be used in larger IaC solutions by calling the class called S3ToAzureBackupService and providing the Azure credentials and client secret as properties to the constructor.
import * as cdk from "aws-cdk-lib";
import { Construct } from "constructs";
import { S3ToAzureBackupService } from "./s3-to-azure-backup-service";

export class MultiCloudBackupCdkStack extends cdk.Stack {
  constructor(scope: Construct, id: string, props?: cdk.StackProps) {
    super(scope, id, props);

    const s3ToAzureBackupService = new S3ToAzureBackupService(
      this,
      "MyMultiCloudBackupService",
      "/s3toazurebackupservice/azuresubscriptionid",
      "/s3toazurebackupservice/azureclientid",
      "/s3toazurebackupservice/azuretenantid",
      "s3toazurebackupservice/azureclientsecret"
    );
  }
}
Solution Diagram
Diagram 1: IaC Single Control Plane, demonstrates the concept of the Azure Blob Storage extension being imported from the AWS CloudFormation Registry into AWS CDK as an L1 CfnResource, wrapped into an L2 Construct and used in an L3 pattern alongside AWS resources to perform the specific task of backing up from and Amazon s3 Bucket into an Azure Blob Storage Container.
Diagram 1: IaC Single Control Plan
The CDK application is then synthesized into one or more AWS CloudFormation Templates, which result in the CloudFormation service deploying AWS resource configurations to AWS and Azure resource configurations to Azure.
This solution demonstrates not only how to consolidate the management of secondary cloud resources into a unified infrastructure stack in AWS, but also the improved productivity by eliminating the complexity and cost of operating multiple deployment mechanisms into multiple public cloud environments.
The following video demonstrates an example in real-time of the end-state solution:
Next Steps
While this was just a straightforward example, with the same approach you can use your imagination to come up with even more and complex scenarios where AWS CDK can be used as a single pane of glass for IaC to manage multicloud and hybrid solutions.
To get started with the solution discussed in this post, this workshop will provide you with the instructions you need to understand the steps required to create the S3ToAzureBackupService.
Once you have learned how to create AWS CloudFormation extensions and develop them into AWS CDK Constructs, you will learn how, with just a few lines of code, you can develop reusable multicloud unified IaC solutions that deploy through a single AWS control plane.
Conclusion
By adopting AWS CloudFormation extensions and AWS CDK, deployed through a single AWS control plane, the cost and complexity of maintaining deployment pipelines across multiple cloud providers is reduced to a single holistic solution-focused pipeline. The techniques demonstrated in this post and the related workshop provide a capability to simplify the design of complex systems, improve the management of integration, and more closely align the IaC and deployment management practices with the design.
Over the past few decades, digital technologies have brought tremendous benefits to our societies, governments, businesses, and everyday lives. However, the more we depend on them for critical applications, the more we must do so securely. The increasing reliance on these systems comes with a broad responsibility for society, companies, and governments.
At Amazon Web Services (AWS), every employee, regardless of their role, works to verify that security is an integral component of every facet of the business (see Security at AWS). This goes hand-in-hand with new cybersecurity-related regulations, such as the Directive on Measures for a High Common Level of Cybersecurity Across the Union (NIS 2), formally adopted by the European Parliament and the Counsel of the European Union (EU) in December 2022. NIS 2 will be transposed into the national laws of the EU Member States by October 2024, and aims to strengthen cybersecurity across the EU.
AWS is excited to help customers become more resilient, and we look forward to even closer cooperation with national cybersecurity authorities to raise the bar on cybersecurity across Europe. Building society’s trust in the online environment is key to harnessing the power of innovation for social and economic development. It’s also one of our core Leadership Principles: Success and scale bring broad responsibility.
Compliance with NIS 2
NIS 2 seeks to ensure that entities mitigate the risks posed by cyber threats, minimize the impact of incidents, and protect the continuity of essential and important services in the EU.
Besides increased cooperation between authorities and support for enhanced information sharing amongst covered entities, NIS 2 includes minimum requirements for cybersecurity risk management measures and reporting obligations, which are applicable to a broad range of AWS customers based on their sector. Examples of sectors that must comply with NIS 2 requirements are energy, transport, health, public administration, and digital infrastructures. For the full list of covered sectors, see Annexes I and II of NIS 2. Generally, the NIS 2 Directive applies to a wider pool of entities than those currently covered by the NIS Directive, including medium-sized enterprises, as defined in Article 2 of the Annex to Recommendation 2003/361/EC (over 50 employees or an annual turnover over €10 million).
In several countries, aspects of the AWS service offerings are already part of the national critical infrastructure. For example, in Germany, Amazon Elastic Compute Cloud (Amazon EC2) and Amazon CloudFront are in scope for the KRITIS regulation. For several years, AWS has fulfilled its obligations to secure these services, run audits related to national critical infrastructure, and have established channels for exchanging security information with the German Federal Office for Information Security (BSI) KRITIS office. AWS is also part of the UP KRITIS initiative, a cooperative effort between industry and the German Government to set industry standards.
AWS will continue to support customers in implementing resilient solutions, in accordance with the shared responsibility model. Compliance efforts within AWS will include implementing the requirements of the act and setting out technical and methodological requirements for cloud computing service providers, to be published by the European Commission, as foreseen in Article 21 of NIS 2.
AWS cybersecurity risk management – Current status
Even before the introduction of NIS 2, AWS has been helping customers improve their resilience and incident response capacities. Our core infrastructure is designed to satisfy the security requirements of the military, global banks, and other highly sensitive organizations.
AWS provides information and communication technology services and building blocks that businesses, public authorities, universities, and individuals use to become more secure, innovative, and responsive to their own needs and the needs of their customers. Security and compliance remain a shared responsibility between AWS and the customer. We make sure that the AWS cloud infrastructure complies with applicable regulatory requirements and good practices for cloud providers, and customers remain responsible for building compliant workloads in the cloud.
In total, AWS supports or has obtained over 143 security standards compliance certifications and attestations around the globe, such as ISO 27001, ISO 22301, ISO 20000, ISO 27017, and System and Organization Controls (SOC) 2. The following are some examples of European certifications and attestations that we’ve achieved:
C5 — provides a wide-ranging control framework for establishing and evidencing the security of cloud operations in Germany.
ENS High — comprises principles for adequate protection applicable to government agencies and public organizations in Spain.
HDS — demonstrates an adequate framework for technical and governance measures to secure and protect personal health data, governed by French law.
Pinakes — provides a rating framework intended to manage and monitor the cybersecurity controls of service providers upon which Spanish financial entities depend.
These and other AWS Compliance Programs help customers understand the robust controls in place at AWS to help ensure the security and compliance of the cloud. Through dedicated teams, we’re prepared to provide assurance about the approach that AWS has taken to operational resilience and to help customers achieve assurance about the security and resiliency of their workloads. AWS Artifact provides on-demand access to these security and compliance reports and many more.
For security in the cloud, it’s crucial for our customers to make security by design and security by default central tenets of product development. To begin with, customers can use the AWS Well-Architected tool to help build secure, high-performing, resilient, and efficient infrastructure for a variety of applications and workloads. Customers that use the AWS Cloud Adoption Framework (AWS CAF) can improve cloud readiness by identifying and prioritizing transformation opportunities. These foundational resources help customers secure regulated workloads. AWS Security Hub provides customers with a comprehensive view of their security state on AWS and helps them check their environments against industry standards and good practices.
With regards to the cybersecurity risk management measures and reporting obligations that NIS 2 mandates, existing AWS service offerings can help customers fulfill their part of the shared responsibility model and comply with future national implementations of NIS 2. For example, customers can use Amazon GuardDuty to detect a set of specific threats to AWS accounts and watch out for malicious activity. Amazon CloudWatch helps customers monitor the state of their AWS resources. With AWS Config, customers can continually assess, audit, and evaluate the configurations and relationships of selected resources on AWS, on premises, and on other clouds. Furthermore, AWS Whitepapers, such as the AWS Security Incident Response Guide, help customers understand, implement, and manage fundamental security concepts in their cloud architecture.
At Amazon, we strive to be the world’s most customer-centric company. For AWS Security Assurance, that means having teams that continuously engage with authorities to understand and exceed regulatory and customer obligations on behalf of customers. This is just one way that we raise the security bar in Europe. At the same time, we recommend that national regulators carefully assess potentially conflicting, overlapping, or contradictory measures.
We also cooperate with cybersecurity agencies around the globe because we recognize the importance of their role in keeping the world safe. To that end, we have built the Global Cybersecurity Program (GCSP) to provide agencies with a direct and consistent line of communication to the AWS Security team. Two examples of GCSP members are the Dutch National Cyber Security Centrum (NCSC-NL), with whom we signed a cooperation in May 2023, and the Italian National Cybersecurity Agency (ACN). Together, we will work on cybersecurity initiatives and strengthen the cybersecurity posture across the EU. With the war in Ukraine, we have experienced how important such a collaboration can be. AWS has played an important role in helping Ukraine’s government maintain continuity and provide critical services to citizens since the onset of the war.
The way forward
At AWS, we will continue to provide key stakeholders with greater insights into how we help customers tackle their most challenging cybersecurity issues and provide opportunities to deep dive into what we’re building. We very much look forward to continuing our work with authorities, agencies and, most importantly, our customers to provide for the best solutions and raise the bar on cybersecurity and resilience across the EU and globally.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
Every software component built by engineers and architects is designed with a purpose: to offer particular functionalities and, ultimately, contribute to the generation of business value. We should consider fundamental factors, such as the scalability of the software and the ease of evolution during times of business changes. However, performance and cost are important factors as well since they can impact the business profitability.
This edition of Let’s Architect! follows a similar series post from 2022, which discusses optimizing the cost of an architecture. Today, we focus on architectural patterns, services, and best practices to design cost-optimized cloud workloads. We also want to identify solutions, such as the use of Graviton processors, for increased performance at lower price. Cost optimization is a continuous process that requires the identification of the right tools for each job, as well as the adoption of efficient designs for your system.
Govern cloud usage and avoid cost surprises without slowing down innovation within your organization. In this re:Invent 2022 session, you can learn how to set up guardrails and operationalize cost control within your organizations using services, such as AWS Budgets and AWS Cost Anomaly Detection, and explore the latest enhancements in the AWS cost control space. Additionally, Mercado Libre shares how they automate their cloud cost control through central management and automated algorithms.
Work backwards from team needs to define/deploy cloud governance in AWS environments
Compute optimization
When it comes to optimizing compute workloads, there are many tools available, such as AWS Compute Optimizer, Amazon EC2 Spot Instances, Amazon EC2 Reserved Instances, and Graviton instances. Modernizing your applications can also lead to cost savings, but you need to know how to use the right tools and techniques in an effective and efficient way.
For AWS Lambda functions, you can use the AWS Lambda Cost Optimization video to learn how to optimize your costs. The video covers topics, such as understanding and graphing performance versus cost, code optimization techniques, and avoiding idle wait time. If you are using Amazon Elastic Container Service (Amazon ECS) and AWS Fargate, you can watch a Twitch video on cost optimization using Amazon ECS and AWS Fargate to learn how to adjust your costs. The video covers topics like using spot instances, choosing the right instance type, and using Fargate Spot.
The choice of the hardware is a fundamental driver for performance, cost, as well as resource consumption of the systems we build. Graviton is a family of processors designed by AWS to support cloud-based workloads and give improvements in terms of performance and cost. This re:Invent 2022 presentation introduces Graviton and addresses the problems it can solve, how the underlying CPU architecture is designed, and how to get started with it. Furthermore, you can learn the journey to move different types of workloads to this architecture, such as containers, Java applications, and C applications.
The Cost Optimization section of the AWS Well Architected Workshop helps you learn how to optimize your AWS costs by using features, such as AWS Compute Optimizer, Spot Instances, and Reserved Instances. The workshop includes hands-on labs that walk you through the process of optimizing costs for different types of workloads and services, such as Amazon Elastic Compute Cloud, Amazon ECS, and Lambda.
At AWS, we’re committed to helping our customers meet digital sovereignty requirements. Last year, I announced the AWS Digital Sovereignty Pledge, our commitment to offering all AWS customers the most advanced set of sovereignty controls and features available in the cloud. Our approach is to continue to make AWS sovereign-by-design—as it has been from day one.
I promised that our pledge was just the start, and that we would continue to innovate to meet the needs of our customers. As part of our promise, we pledged to invest in an ambitious roadmap of capabilities on data residency, granular access restriction, encryption, and resilience. Today, I’d like to update you on another milestone on our journey to continue to help our customers address their sovereignty needs.
Further control over the location of your data
Customers have always controlled the location of their data with AWS. For example, in Europe, customers have the choice to deploy their data into any of eight existing AWS Regions. These AWS Regions provide the broadest set of cloud services and features, enabling our customers to run the majority of their workloads. Customers can also use AWS Local Zones, a type of infrastructure deployment that makes AWS services available in more places, to help meet latency and data residency requirements, without having to deploy self-managed infrastructure. Customers who must comply with data residency regulations can choose to run their workloads in specific geographic locations where AWS Regions and Local Zones are available.
Announcing AWS Dedicated Local Zones
Our public sector and regulated industry customers have told us they want dedicated infrastructure for their most critical workloads to help meet regulatory or other compliance requirements. Many of these customers manage their own infrastructure on premises for workloads that require isolation. This forgoes the performance, innovation, elasticity, scalability, and resiliency benefits of the cloud.
To help our customers address these needs, I’m excited to announce AWS Dedicated Local Zones. Dedicated Local Zones are a type of AWS infrastructure that is fully managed by AWS, built for exclusive use by a customer or community, and placed in a customer-specified location or data center to help comply with regulatory requirements. Dedicated Local Zones can be operated by local AWS personnel and offer the same benefits of Local Zones, such as elasticity, scalability, and pay-as-you-go pricing, with added security and governance features. These features include data access monitoring and audit programs, controls to limit infrastructure access to customer-selected AWS accounts, and options to enforce security clearance or other criteria on local AWS operating personnel. With Dedicated Local Zones, we work with customers to configure their own Local Zones with the services and capabilities they need to meet their regulatory requirements.
Innovating with the Singapore Government’s Smart Nation and Digital Government Group
At AWS, we work closely with customers to understand their requirements for their most critical workloads. Our work with the Singapore Government’s Smart Nation and Digital Government Group (SNDGG) to build a Smart Nation for their citizens and businesses illustrates this approach. This group spearheads Singapore’s digital government transformation and development of the public sector’s engineering capabilities. SNDGG is the first customer to deploy Dedicated Local Zones.
“AWS is a strategic partner and has been since the beginning of our cloud journey. SNDGG collaborated with AWS to define and build Dedicated Local Zones to help us meet our stringent data isolation and security requirements, enabling Singapore to run more sensitive workloads in the cloud securely,” said Chan Cheow Hoe, Government Chief Digital Technology Officer of Singapore. “In addition to helping the Singapore government meet its cybersecurity requirements, the Dedicated Local Zones enable us to offer its agencies a seamless and consistent cloud experience.”
Our commitments to our customers
We remain committed to helping our customers meet evolving sovereignty requirements. We continue to innovate sovereignty features, controls, and assurances globally with AWS, without compromising on the full power of AWS.
To get started, you can visit the Dedicated Local Zones website, where you can contact AWS specialists to learn more about how Dedicated Local Zones can be configured to meet your regulatory needs.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
Product security teams play a critical role to help ensure that new services, products, and features are built and shipped securely to customers. However, since security teams are in the product launch path, they can form a bottleneck if organizations struggle to scale their security teams to support their growing product development teams. In this post, we will share how Amazon Web Services (AWS) developed a mechanism to scale security processes and expertise by distributing security ownership between security teams and development teams. This mechanism has many names in the industry — Security Champions, Security Advocates, and others — and it’s often part of a shift-left approach to security. At AWS, we call this mechanism Security Guardians.
In many organizations, there are fewer security professionals than product developers. Our experience is that it takes much more time to hire a security professional than other technical job roles, and research conducted by (ISC)2 shows that the cybersecurity industry is short 3.4 million workers. When product development teams continue to grow at a faster rate than security teams, the disparity between security professionals and product developers continues to increase as well. Although most businesses understand the importance of security, frustration and tensions can arise when it becomes a bottleneck for the business and its ability to serve customers.
At AWS, we require the teams that build products to undergo an independent security review with an AWS application security engineer before launching. This is a mechanism to verify that new services, features, solutions, vendor applications, and hardware meet our high security bar. This intensive process impacts how quickly product teams can ship to customers. As shown in Figure 1, we found that as the product teams scaled, so did the problem: there were more products being built than the security teams could review and approve for launch. Because security reviews are required and non-negotiable, this could potentially lead to delays in the shipping of products and features.
Figure 1: More products are being developed than can be reviewed and shipped
How AWS builds a culture of security
Because of its size and scale, many customers look to AWS to understand how we scale our own security teams. To tell our story and provide insight, let’s take a look at the culture of security at AWS.
Security is a business priority
At AWS, security is a business priority. Business leaders prioritize building products and services that are designed to be secure, and they consider security to be an enabler of the business rather than an obstacle.
Leaders also strive to create a safe environment by encouraging employees to identify and escalate potential security issues. Escalation is the process of making sure that the right people know about the problem at the right time. Escalation encompasses “Dive Deep”, which is one of our corporate values at Amazon, because it requires owners and leaders to dive into the details of the issue. If you don’t know the details, you can’t make good decisions about what’s going on and how to run your business effectively.
This aspect of the culture goes beyond intention — it’s embedded in our organizational structure:
CISOs and IT leaders play a key role in demystifying what security and compliance represent for the business. At AWS, we made an intentional choice for the security team to report directly to the CEO. The goal was to build security into the structural fabric of how AWS makes decisions, and every week our security team spends time with AWS leadership to ensure we’re making the right choices on tactical and strategic security issues.
Because our leadership supports security, it’s understood within AWS that security is everyone’s job. Security teams and product development teams work together to help ensure that products are built and shipped securely. Despite this collaboration, the product teams own the security of their product. They are responsible for making sure that security controls are built into the product and that customers have the tools they need to use the product securely.
On the other hand, central security teams are responsible for helping developers to build securely and verifying that security requirements are met before launch. They provide guidance to help developers understand what security controls to build, provide tools to make it simpler for developers to implement and test controls, provide support in threat modeling activities, use mechanisms to help ensure that customers’ security expectations are met before launch, and so on.
This responsibility model highlights how security ownership is distributed between the security and product development teams. At AWS, we learned that without this distribution, security doesn’t scale. Regardless of the number of security experts we hire, product teams always grow faster. Although the culture around security and the need to distribute ownership is now well understood, without the right mechanisms in place, this model would have collapsed.
Mechanisms compared to good intentions
Mechanisms are the final pillar of AWS culture that has allowed us to successfully distribute security across our organization. A mechanism is a complete process, or virtuous cycle, that reinforces and improves itself as it operates. As shown in Figure 2, a mechanism takes controllable inputs and transforms them into ongoing outputs to address a recurring business challenge. At AWS, the business challenge that we’re facing is that security teams create bottlenecks for the business. The culture of security at AWS provides support to help address this challenge, but we needed a mechanism to actually do it.
Figure 2: AWS sees mechanisms as a complete process, or virtuous cycle
“Often, when we find a recurring problem, something that happens over and over again, we pull the team together, ask them to try harder, do better – essentially, we ask for good intentions. This rarely works… When you are asking for good intentions, you are not asking for a change… because people already had good intentions. But if good intentions don’t work, what does? Mechanisms work.
At AWS, we’ve learned that we can help solve the challenge of scaling security by distributing security ownership with a mechanism we call the Security Guardians program. Like other mechanisms, it has inputs and outputs, and transforms over time.
AWS distributes security ownership with the Security Guardians program
At AWS, the Security Guardians program trains, develops, and empowers developers to be security ambassadors, or Guardians, within the product teams. At a high level, Guardians make sure that security considerations for a product are made earlier and more often, helping their peers build and ship their product faster. They also work closely with the central security team to help ensure that the security bar at AWS is rising and the Security Guardians program is improving over time. As shown in Figure 3, embedding security expertise within the product teams helps products with Guardian involvement move through security review faster.
Figure 3: Security expertise is embedded in the product teams by Guardians
Guardians are informed, security-minded product builders who volunteer to be consistent champions of security on their teams and are deeply familiar with the security processes and tools. They provide security guidance throughout the development lifecycle and are stakeholders in the security of the products being shipped, helping their teams make informed decisions that lead to more secure, on-time launches. Guardians are the security points-of-contact for their product teams.
In this distributed security ownership model, accountability for product security sits with the product development teams. However, the Guardians are responsible for performing the first evaluation of a development team’s security review submission. They confirm the quality and completeness of the new service’s resources, design documents, threat model, automated findings, and penetration test readiness. The development teams, supported by the Guardian, submit their security review to AWS Application Security (AppSec) engineers for the final pre-launch review.
In practice, as part of this development journey, Guardians help ensure that security considerations are made early, when teams are assessing customer requests and the feature or product design. This can be done by starting the threat modeling processes. Next, they work to make sure that mitigations identified during threat modeling are developed. Guardians also play an active role in software testing, including security scans such as static application security testing (SAST) and dynamic application security testing (DAST). To close out the security review, security engineers work with Guardians to make sure that findings are resolved and the product is ready to ship.
Figure 4: Expedited security review process supported by Guardians
Guardians are, after all, Amazonians. Therefore, Guardians exemplify a number of the Amazon Leadership Principles and often have the following characteristics:
They are exemplary practitioners for security ownership and empower their teams to own the security of their service.
They hold a high security bar and exercise strong security judgement, don’t accept quick or easy answers, and drive continuous improvement.
They advocate for security needs in internal discussions with the product team.
They are thoughtful yet assertive to make customer security a top priority on their team.
They maintain and showcase their security knowledge to their peers, continuously building knowledge from many different sources to gain perspective and to stay up to date on the constantly evolving threat landscape.
They aren’t afraid to have their work independently validated by the central security team.
Expected outcomes
AWS has benefited greatly from the Security Guardians program. We’ve had 22.5 percent fewer medium and high severity security findings generated during the security review process and have taken about 26.9 percent less time to review a new service or feature. This data demonstrates that with Guardians involved we’re identifying fewer issues late in the process, reducing remediation work, and as a result securely shipping services faster for our customers. To help both builders and Guardians improve over time, our security review tool captures feedback from security engineers on their inputs. This helps ensure that our security ownership mechanism reinforces and improves itself over time.
AWS and other organizations have benefited from this mechanism because it generates specialized security resources and distributes security knowledge that scales without needing to hire additional staff.
A program such as this could help your business build and ship faster, as it has for AWS, while maintaining an appropriately high security bar that rises over time. By training builders to be security practitioners and advocates within your development cycle, you can increase the chances of identifying risks and security findings earlier. These findings, earlier in the development lifecycle, can reduce the likelihood of having to patch security bugs or even start over after the product has already been built. We also believe that a consistent security experience for your product teams is an important aspect of successfully distributing your security ownership. An experience with less confusion and friction will help build trust between the product and security teams.
If you’re an AWS customer and want to learn more about how AWS built the Security Guardians program, reach out to your local AWS solutions architect or account manager for more information.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.

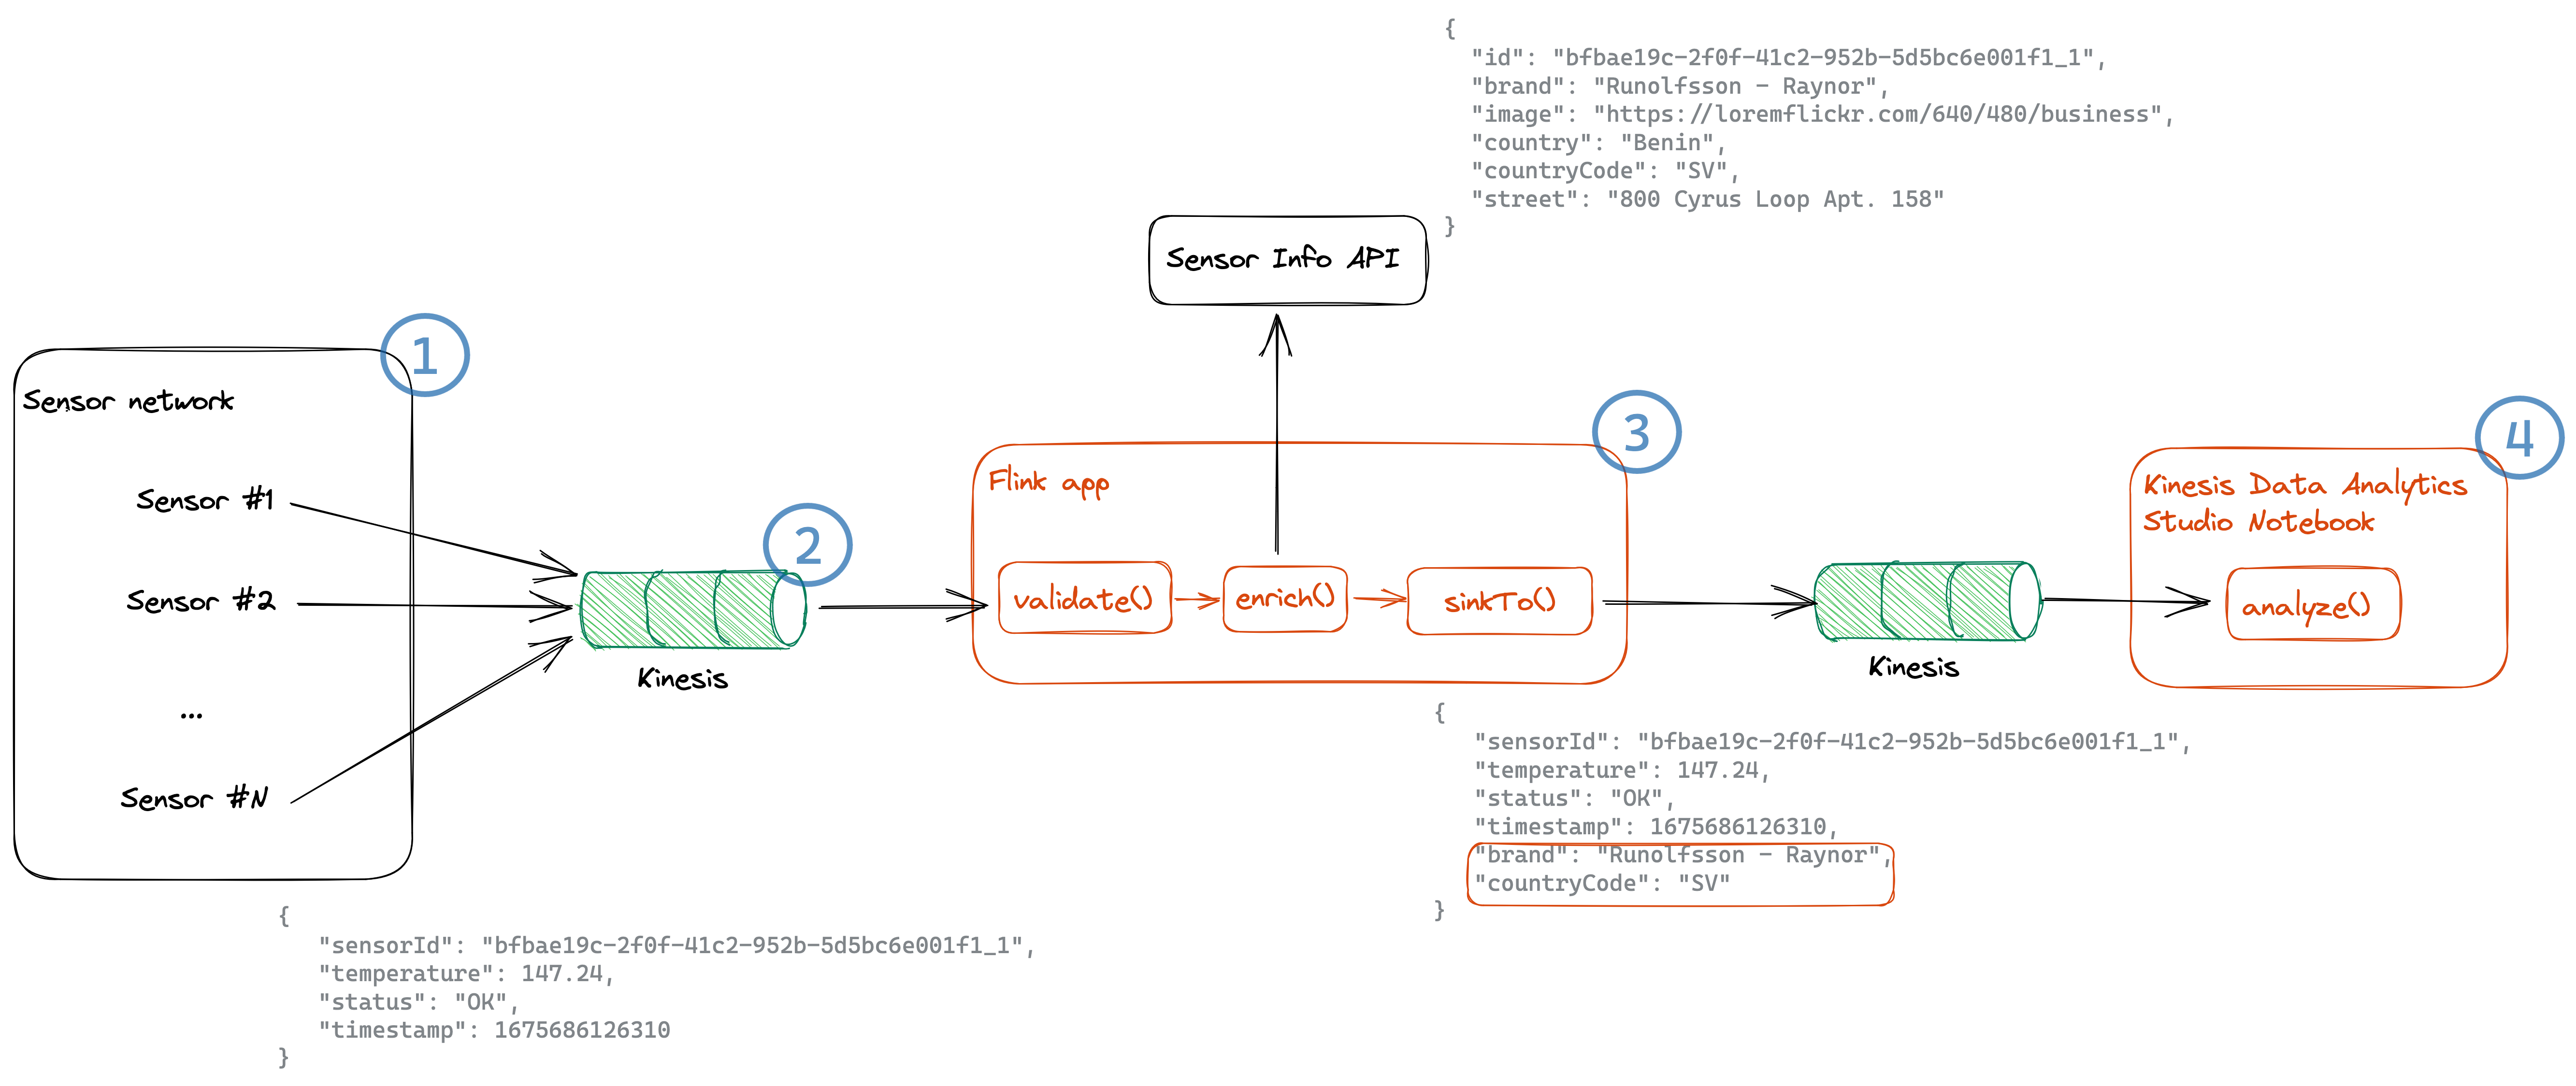
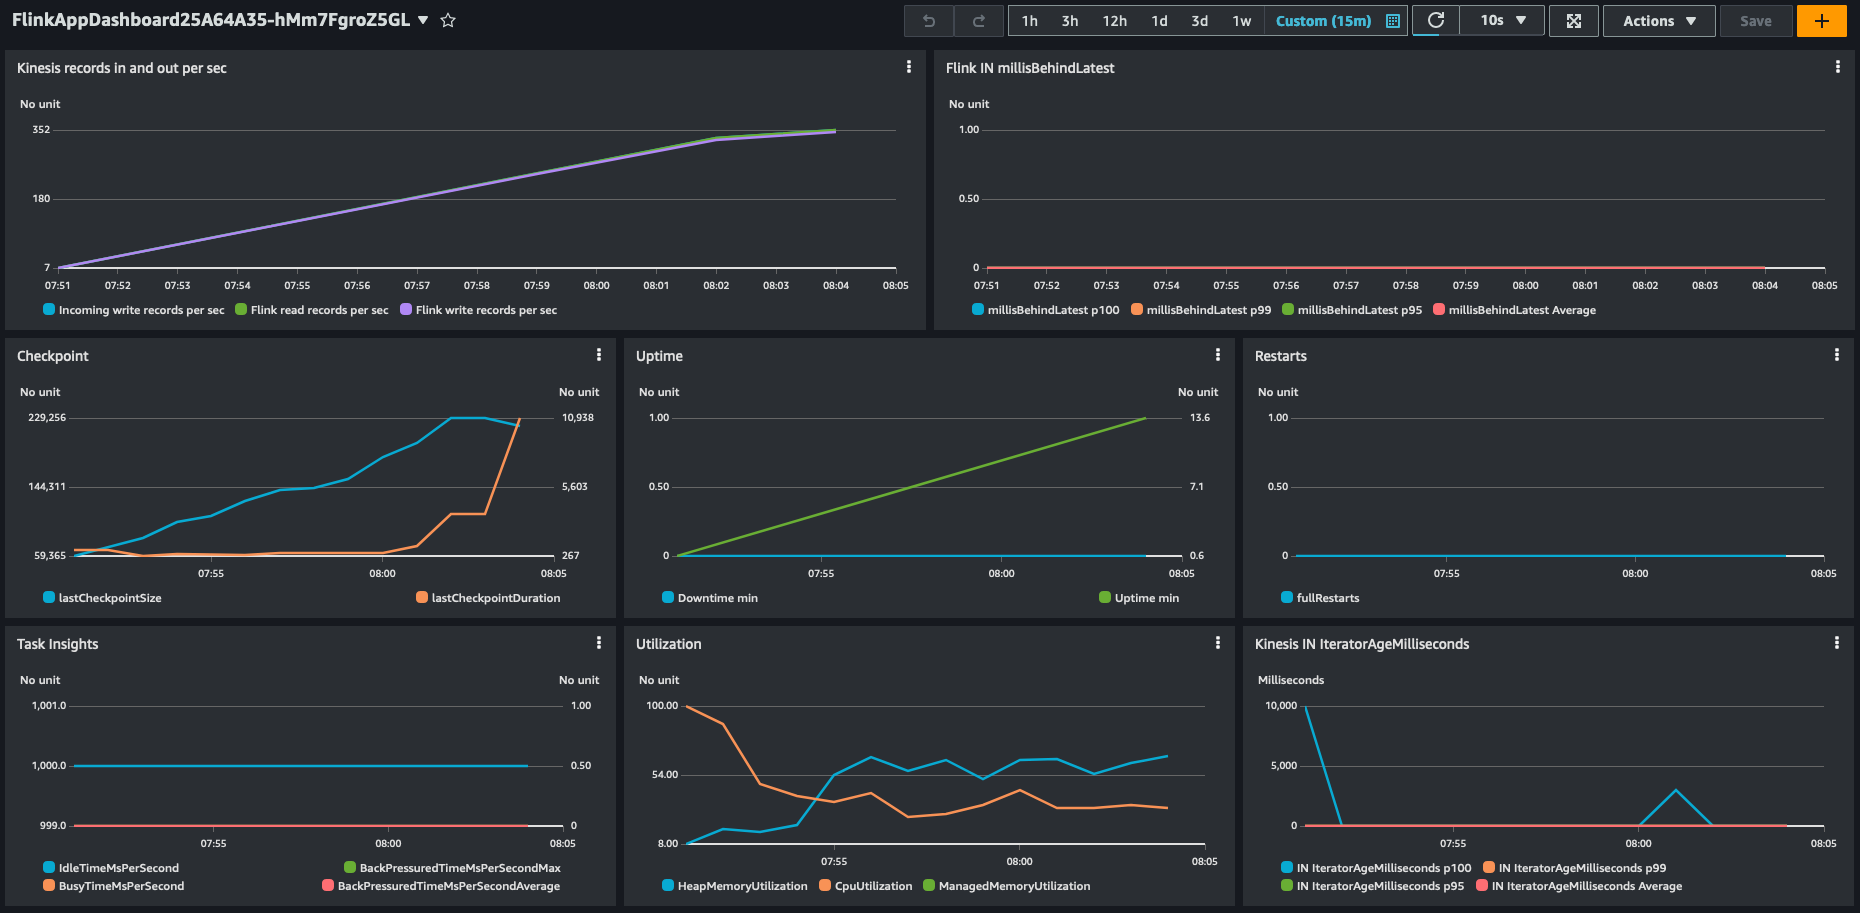
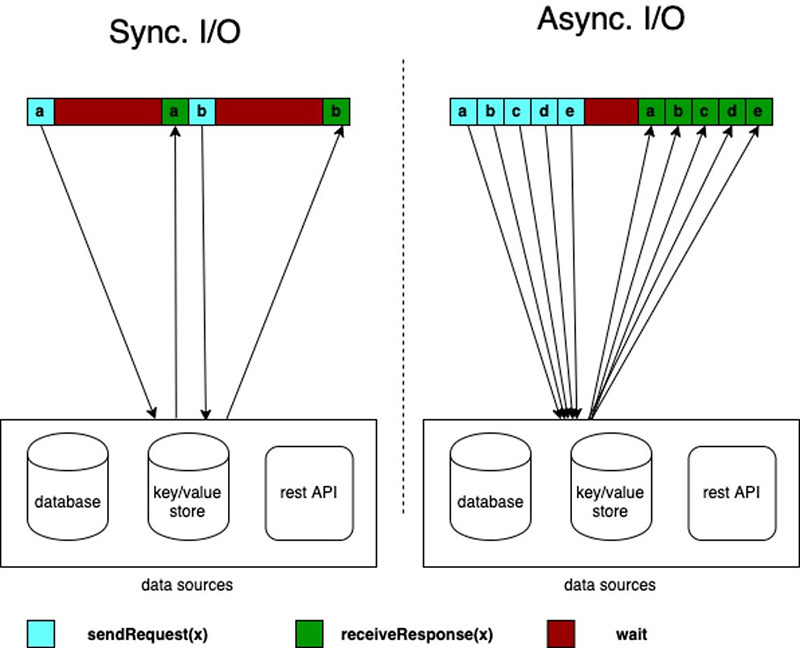
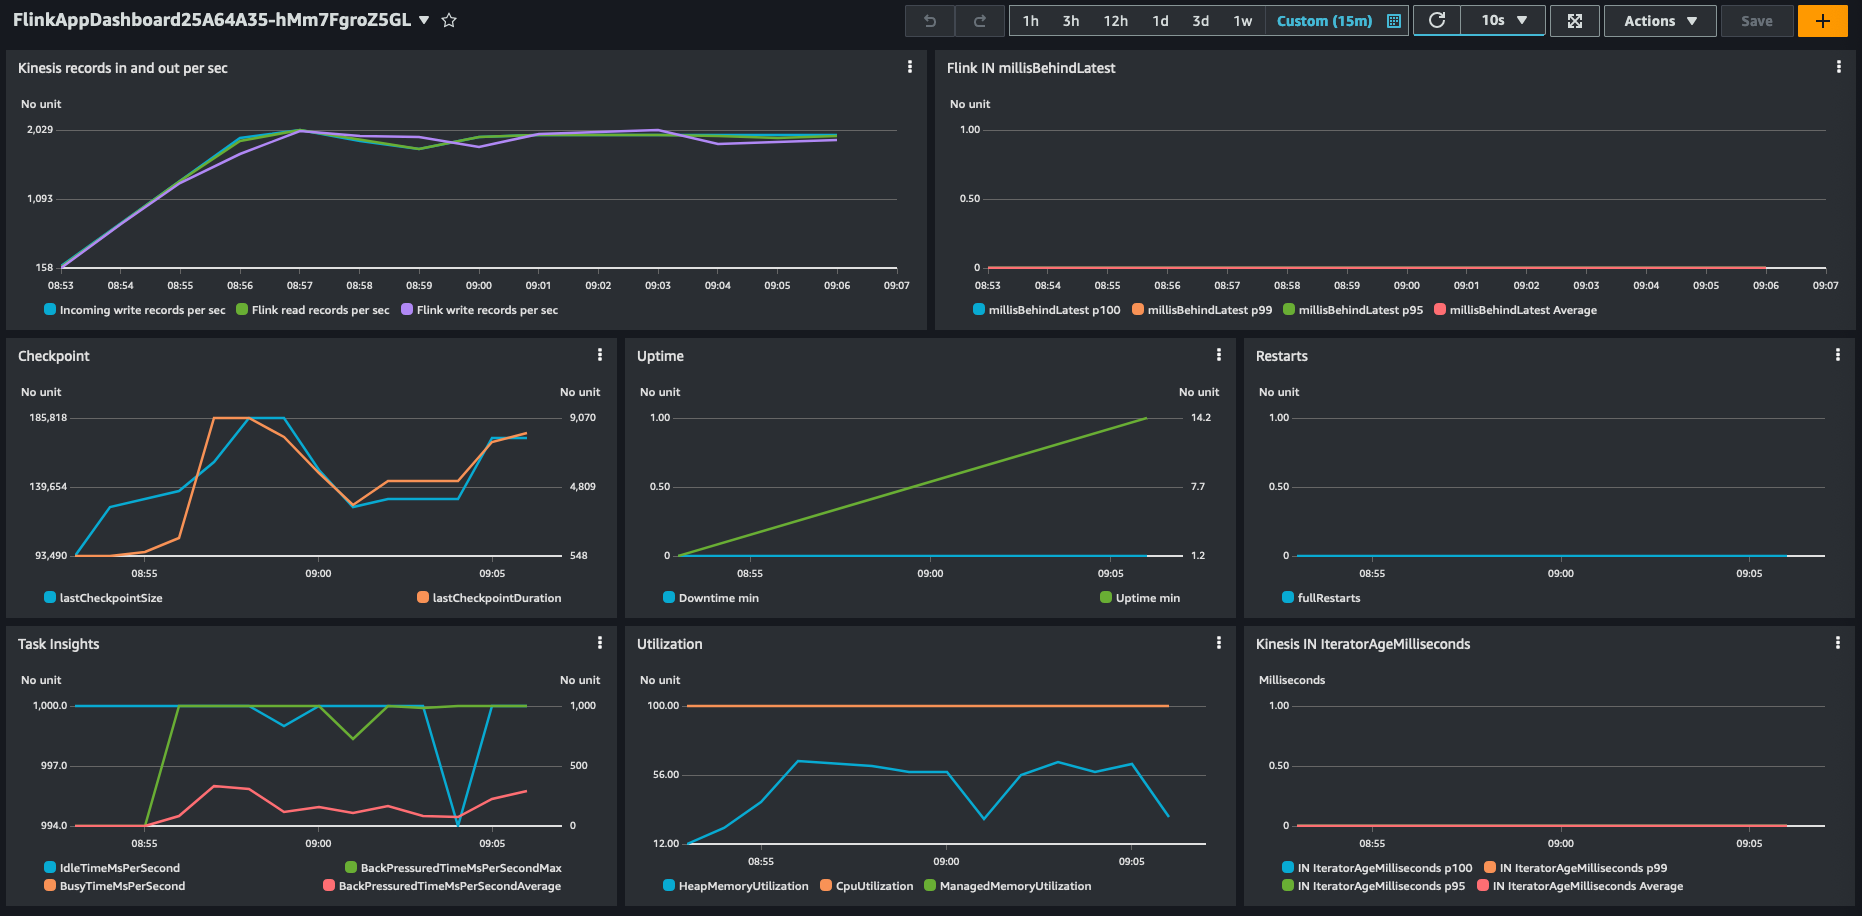
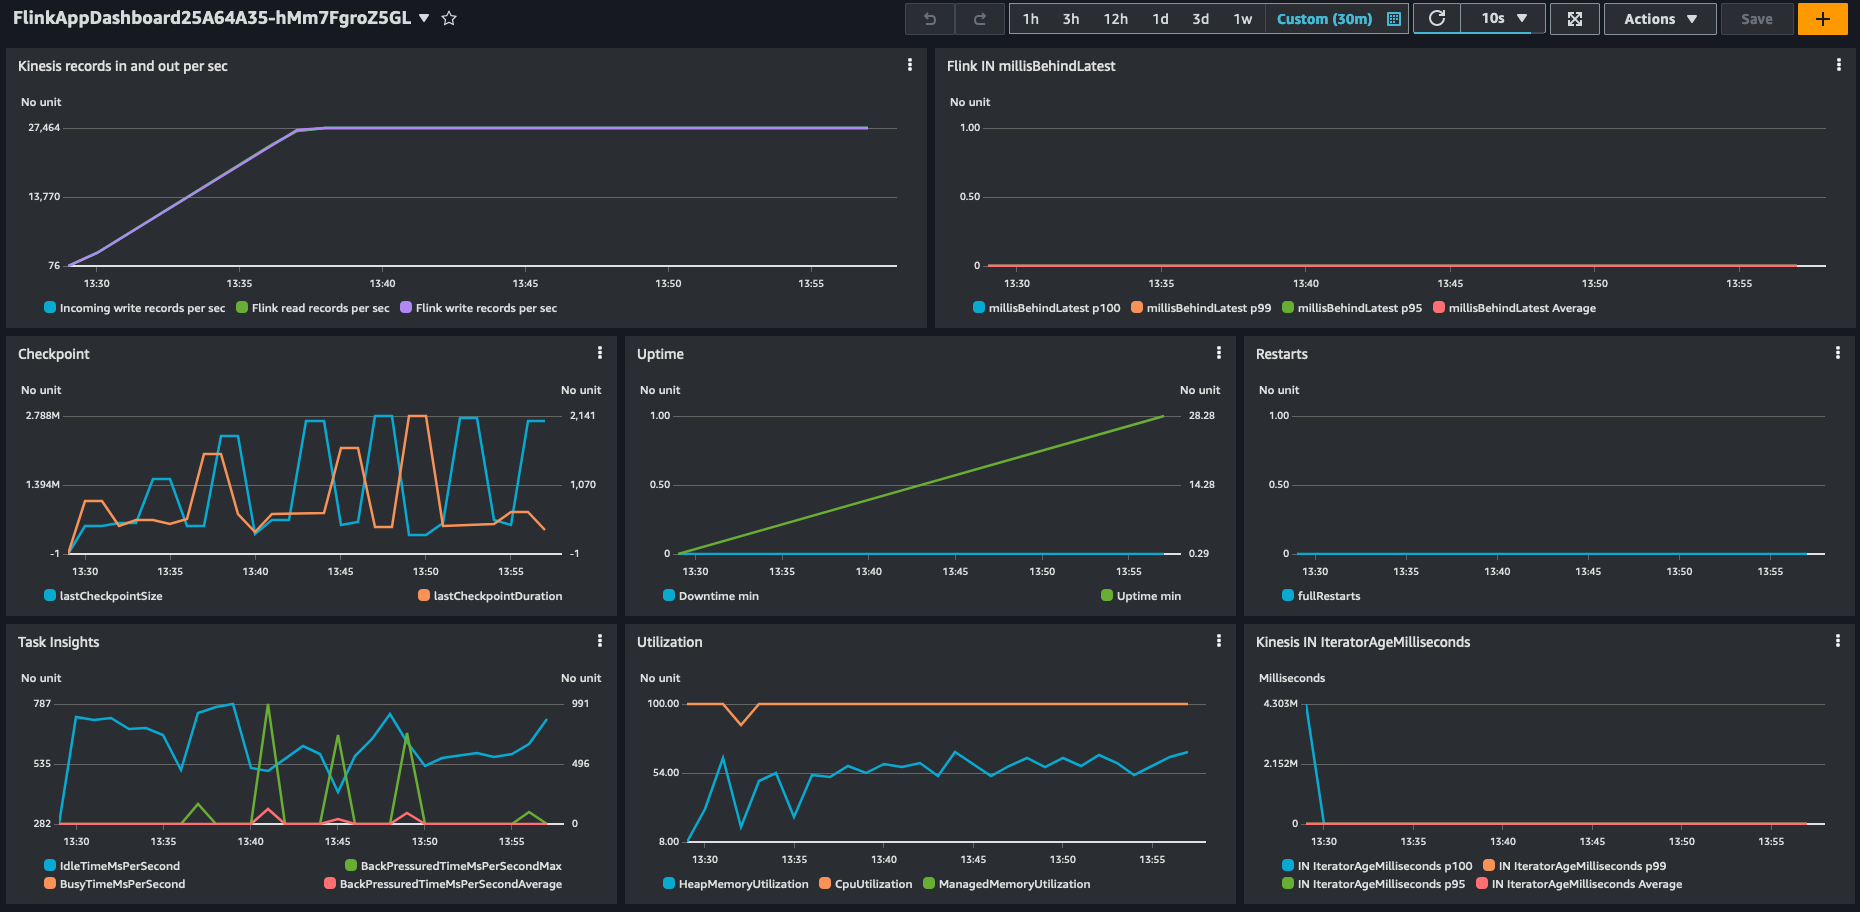
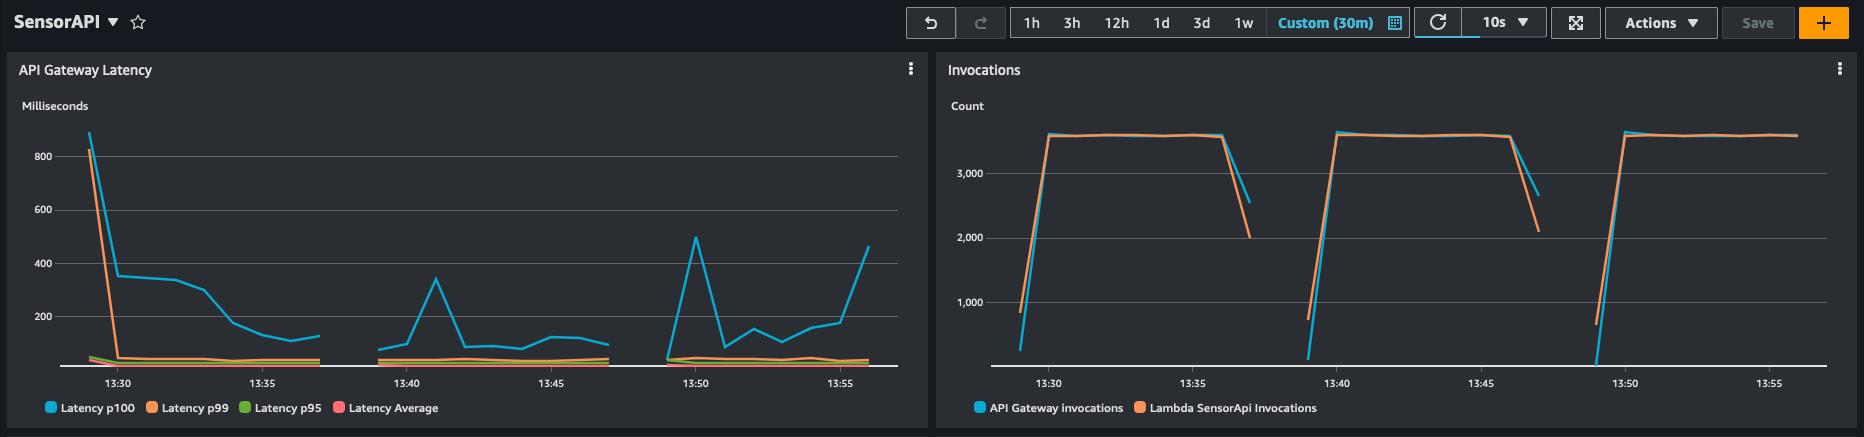
 Luis Morales works as Senior Solutions Architect with digital-native businesses to support them in constantly reinventing themselves in the cloud. He is passionate about software engineering, cloud-native distributed systems, test-driven development, and all things code and security.
 Lorenzo Nicora works as Senior Streaming Solution Architect helping customers across EMEA. He has been building cloud-native, data-intensive systems for several years, working in the finance industry both through consultancies and for fin-tech product companies. He leveraged open source technologies extensively and contributed to several projects, including Apache Flink.


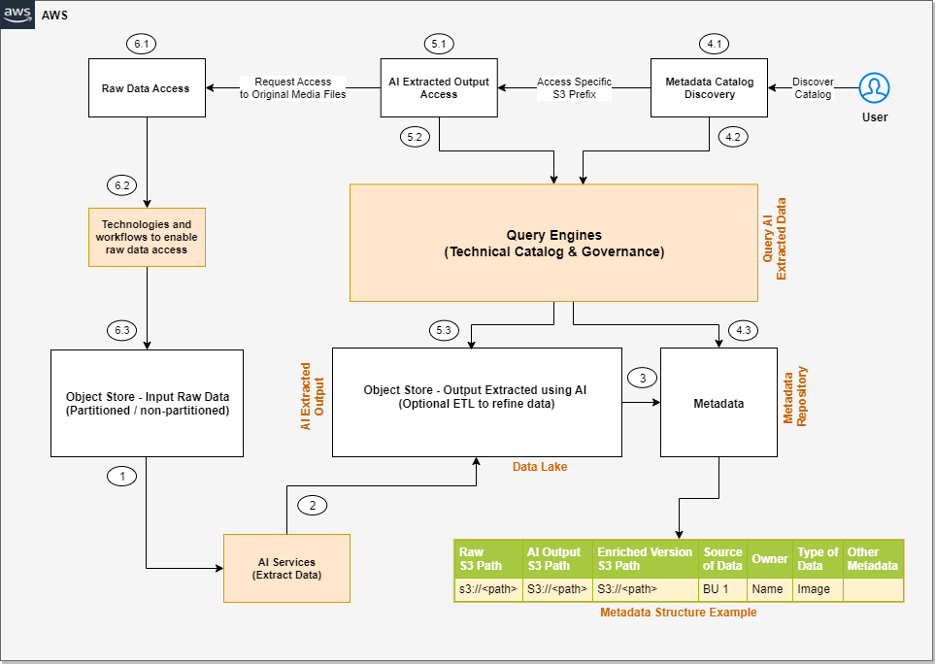

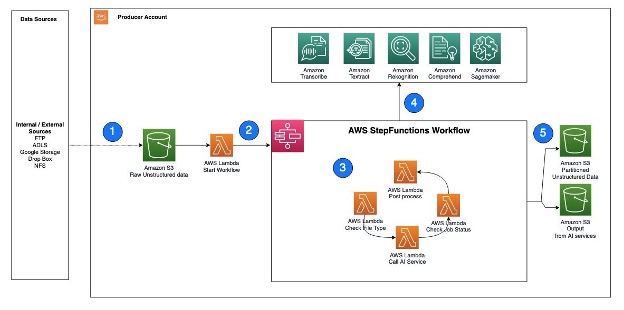
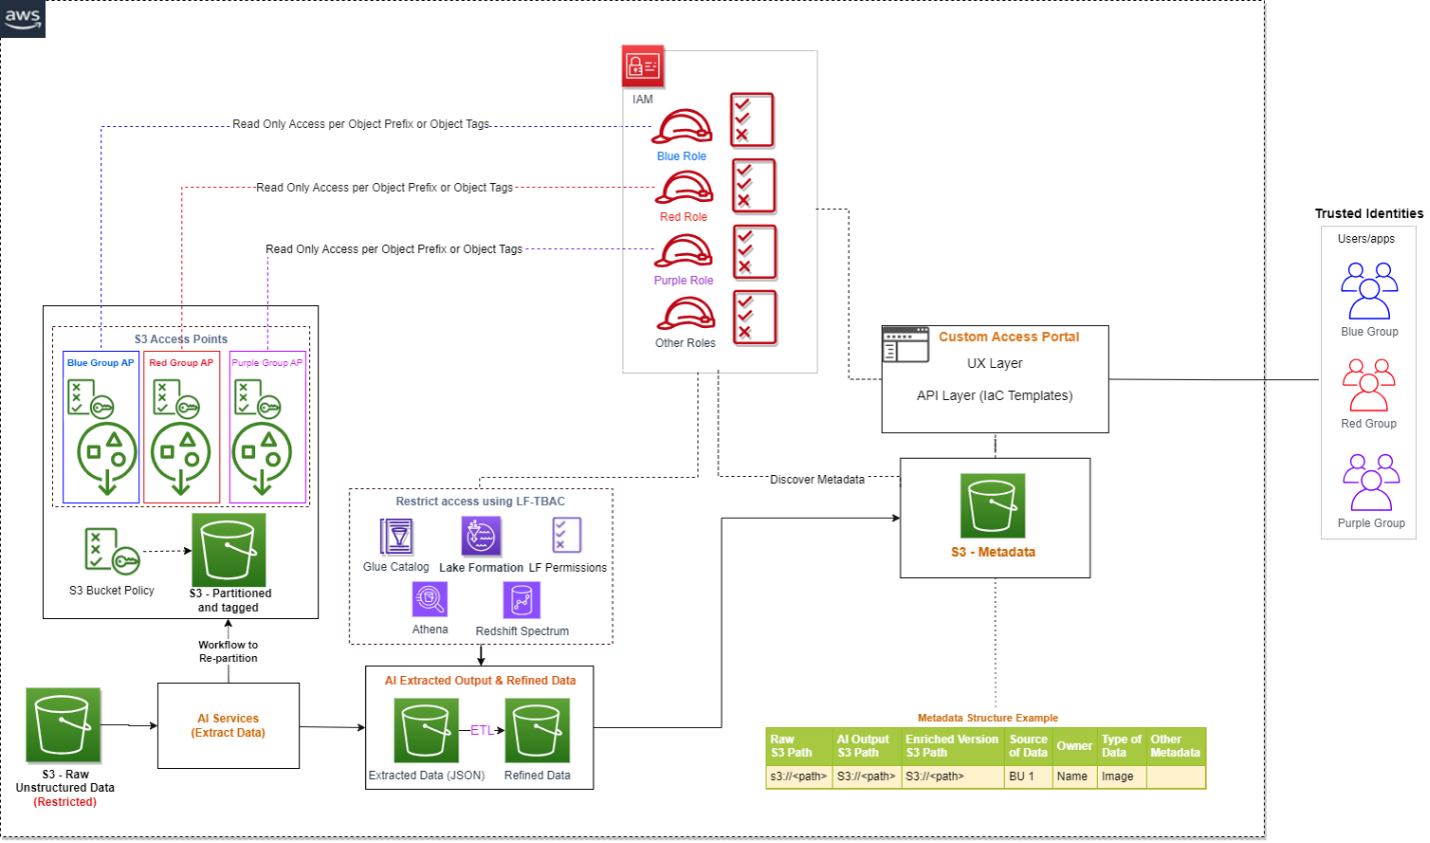
 Sakti Mishra is a Principal Solutions Architect at AWS, where he helps customers modernize their data architecture and define their end-to-end data strategy, including data security, accessibility, governance, and more. He is also the author of the book
 Bhavana Chirumamilla is a Senior Resident Architect at AWS with a strong passion for data and machine learning operations. She brings a wealth of experience and enthusiasm to help enterprises build effective data and ML strategies. In her spare time, Bhavana enjoys spending time with her family and engaging in various activities such as traveling, hiking, gardening, and watching documentaries.
 Sheela Sonone is a Senior Resident Architect at AWS. She helps AWS customers make informed choices and trade-offs about accelerating their data, analytics, and AI/ML workloads and implementations. In her spare time, she enjoys spending time with her family—usually on tennis courts.
 Daniel Bruno is a Principal Resident Architect at AWS. He had been building analytics and machine learning solutions for over 20 years and splits his time helping customers build data science programs and designing impactful ML products.


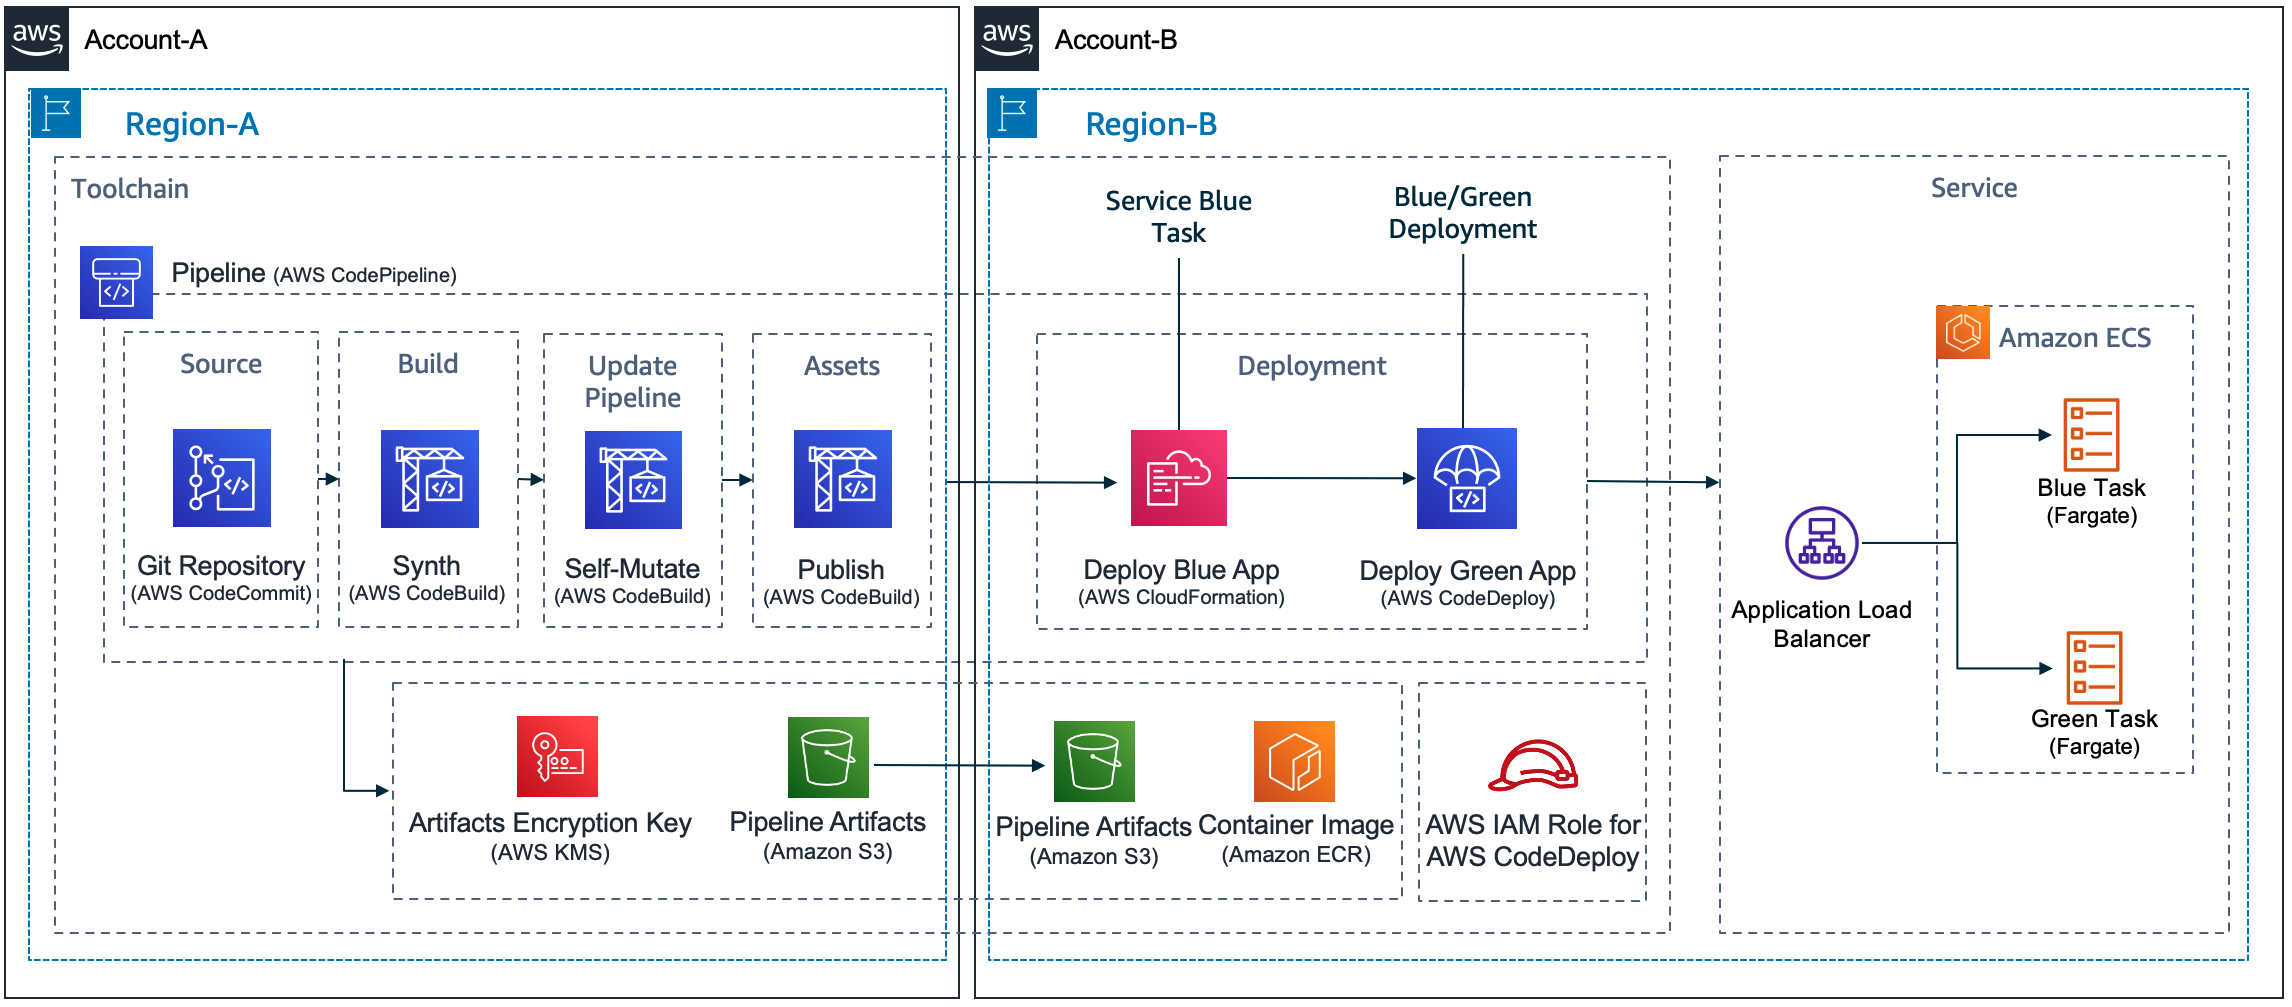


 Shoukat Ghouse is a Senior Big Data Specialist Solutions Architect at AWS. He helps customers around the world build robust, efficient and scalable data platforms on AWS leveraging AWS analytics services like AWS Glue, AWS Lake Formation, Amazon Athena and Amazon EMR.


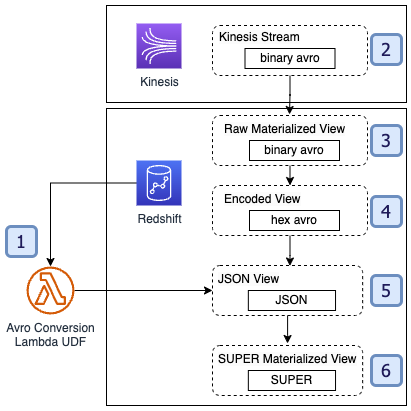
 M Mehrtens has been working in distributed systems engineering throughout their career, working as a Software Engineer, Architect, and Data Engineer. In the past, M has supported and built systems to process terrabytes of streaming data at low latency, run enterprise Machine Learning pipelines, and created systems to share data across teams seamlessly with varying data toolsets and software stacks. At AWS, they are a Sr. Solutions Architect supporting US Federal Financial customers.
 Sindhu Achuthan is a Sr. Solutions Architect with Federal Financials at AWS. She works with customers to provide architectural guidance on analytics solutions using AWS Glue, Amazon EMR, Amazon Kinesis, and other services. Outside of work, she loves DIYs, to go on long trails, and yoga.


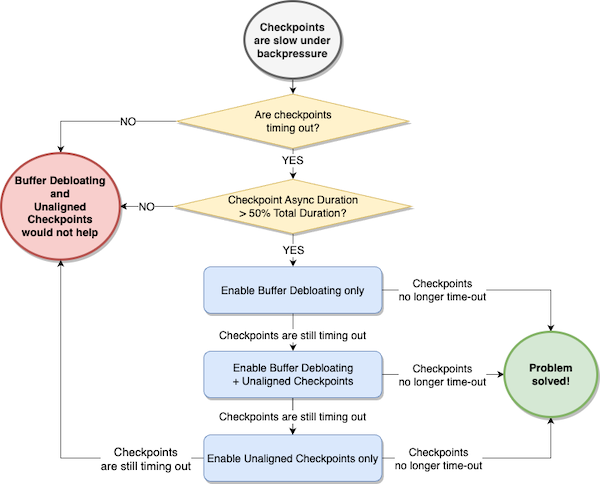
 Lorenzo Nicora works as Senior Streaming Solution Architect helping customers across EMEA. He has been building cloud-native, data-intensive systems for over 25 years, working in the finance industry both through consultancies and for FinTech product companies. He has leveraged open-source technologies extensively and contributed to several projects, including Apache Flink.
 Francisco Morillo is a Streaming Solutions Architect at AWS. Francisco works with AWS customers helping them design real-time analytics architectures using AWS services, supporting Amazon Managed Streaming for Apache Kafka (Amazon MSK) and AWS’s managed offering for Apache Flink.