Tag Archives: Technical How-to

Use multiple bookmark keys in AWS Glue JDBC jobs

Post Syndicated from Durga Prasad original https://aws.amazon.com/blogs/big-data/use-multiple-bookmark-keys-in-aws-glue-jdbc-jobs/

AWS Glue is a serverless data integrating service that you can use to catalog data and prepare for analytics. With AWS Glue, you can discover your data, develop scripts to transform sources into targets, and schedule and run extract, transform, and load (ETL) jobs in a serverless environment. AWS Glue jobs are responsible for running the data processing logic.

One important feature of AWS Glue jobs is the ability to use bookmark keys to process data incrementally. When an AWS Glue job is run, it reads data from a data source and processes it. One or more columns from the source table can be specified as bookmark keys. The column should have sequentially increasing or decreasing values without gaps. These values are used to mark the last processed record in a batch. The next run of the job resumes from that point. This allows you to process large amounts of data incrementally. Without job bookmark keys, AWS Glue jobs would have to reprocess all the data during every run. This can be time-consuming and costly. By using bookmark keys, AWS Glue jobs can resume processing from where they left off, saving time and reducing costs.

This post explains how to use multiple columns as job bookmark keys in an AWS Glue job with a JDBC connection to the source data store. It also demonstrates how to parameterize the bookmark key columns and table names in the AWS Glue job connection options.

This post is focused towards architects and data engineers who design and build ETL pipelines on AWS. You are expected to have a basic understanding of the AWS Management Console, AWS Glue, Amazon Relational Database Service (Amazon RDS), and Amazon CloudWatch logs.

Solution overview

To implement this solution, we complete the following steps:

  1. Create an Amazon RDS for PostgreSQL instance.
  2. Create two tables and insert sample data.
  3. Create and run an AWS Glue job to extract data from the RDS for PostgreSQL DB instance using multiple job bookmark keys.
  4. Create and run a parameterized AWS Glue job to extract data from different tables with separate bookmark keys

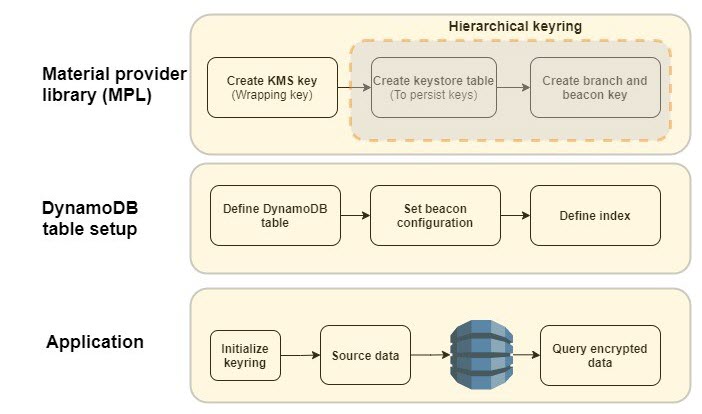
The following diagram illustrates the components of this solution.

Deploy the solution

For this solution, we provide an AWS CloudFormation template that sets up the services included in the architecture, to enable repeatable deployments. This template creates the following resources:

  • An RDS for PostgreSQL instance
  • An Amazon Simple Storage Service (Amazon S3) bucket to store the data extracted from the RDS for PostgreSQL instance
  • An AWS Identity and Access Management (IAM) role for AWS Glue
  • Two AWS Glue jobs with job bookmarks enabled to incrementally extract data from the RDS for PostgreSQL instance

To deploy the solution, complete the following steps:

  1. Choose  to launch the CloudFormation stack:
  2. Enter a stack name.
  3. Select I acknowledge that AWS CloudFormation might create IAM resources with custom names.
  4. Choose Create stack.
  5. Wait until the creation of the stack is complete, as shown on the AWS CloudFormation console.
  6. When the stack is complete, copy the AWS Glue scripts to the S3 bucket job-bookmark-keys-demo-<accountid>.
  7. Open AWS CloudShell.
  8. Run the following commands and replace <accountid> with your AWS account ID:
aws s3 cp s3://aws-blogs-artifacts-public/artifacts/BDB-2907/glue/scenario_1_job.py s3://job-bookmark-keys-demo-<accountid>/scenario_1_job.py
aws s3 cp s3://aws-blogs-artifacts-public/artifacts/BDB-2907/glue/scenario_2_job.py s3://job-bookmark-keys-demo-<accountid>/scenario_2_job.py

Add sample data and run AWS Glue jobs

In this section, we connect to the RDS for PostgreSQL instance via AWS Lambda and create two tables. We also insert sample data into both the tables.

  1. On the Lambda console, choose Functions in the navigation pane.
  2. Choose the function LambdaRDSDDLExecute.
  3. Choose Test and choose Invoke for the Lambda function to insert the data.


The two tables product and address will be created with sample data, as shown in the following screenshot.

Run the multiple_job_bookmark_keys AWS Glue job

We run the multiple_job_bookmark_keys AWS Glue job twice to extract data from the product table of the RDS for PostgreSQL instance. In the first run, all the existing records will be extracted. Then we insert new records and run the job again. The job should extract only the newly inserted records in the second run.

  1. On the AWS Glue console, choose Jobs in the navigation pane.
  2. Choose the job multiple_job_bookmark_keys.
  3. Choose Run to run the job and choose the Runs tab to monitor the job progress.
  4. Choose the Output logs hyperlink under CloudWatch logs after the job is complete.
  5. Choose the log stream in the next window to see the output logs printed.

    The AWS Glue job extracted all records from the source table product. It keeps track of the last combination of values in the columns product_id and version.Next, we run another Lambda function to insert a new record. The product_id 45 already exists, but the inserted record will have a new version as 2, making the combination sequentially increasing.
  6. Run the LambdaRDSDDLExecute_incremental Lambda function to insert the new record in the product table.
  7. Run the AWS Glue job multiple_job_bookmark_keys again after you insert the record and wait for it to succeed.
  8. Choose the Output logs hyperlink under CloudWatch logs.
  9. Choose the log stream in the next window to see only the newly inserted record printed.

The job extracts only those records that have a combination greater than the previously extracted records.

Run the parameterised_job_bookmark_keys AWS Glue job

We now run the parameterized AWS Glue job that takes the table name and bookmark key column as parameters. We run this job to extract data from different tables maintaining separate bookmarks.

The first run will be for the address table with bookmarkkey as address_id. These are already populated with the job parameters.

  1. On the AWS Glue console, choose Jobs in the navigation pane.
  2. Choose the job parameterised_job_bookmark_keys.
  3. Choose Run to run the job and choose the Runs tab to monitor the job progress.
  4. Choose the Output logs hyperlink under CloudWatch logs after the job is complete.
  5. Choose the log stream in the next window to see all records from the address table printed.
  6. On the Actions menu, choose Run with parameters.
  7. Expand the Job parameters section.
  8. Change the job parameter values as follows:
    • Key --bookmarkkey with value product_id
    • Key --table_name with value product
    • The S3 bucket name is unchanged (job-bookmark-keys-demo-<accountnumber>)
  9. Choose Run job to run the job and choose the Runs tab to monitor the job progress.
  10. Choose the Output logs hyperlink under CloudWatch logs after the job is complete.
  11. Choose the log stream to see all the records from the product table printed.

The job maintains separate bookmarks for each of the tables when extracting the data from the source data store. This is achieved by adding the table name to the job name and transformation contexts in the AWS Glue job script.

Clean up

To avoid incurring future charges, complete the following steps:

  1. On the Amazon S3 console, choose Buckets in the navigation pane.
  2. Select the bucket with job-bookmark-keys in its name.
  3. Choose Empty to delete all the files and folders in it.
  4. On the CloudFormation console, choose Stacks in the navigation pane.
  5. Select the stack you created to deploy the solution and choose Delete.

Conclusion

This post demonstrated passing more than one column of a table as jobBookmarkKeys in a JDBC connection to an AWS Glue job. It also explained how you can a parameterized AWS Glue job to extract data from multiple tables while keeping their respective bookmarks. As a next step, you can test the incremental data extract by changing data in the source tables.


About the Authors

Durga Prasad is a Sr Lead Consultant enabling customers build their Data Analytics solutions on AWS. He is a coffee lover and enjoys playing badminton.

Murali Reddy is a Lead Consultant at Amazon Web Services (AWS), helping customers build and implement data analytics solution. When he’s not working, Murali is an avid bike rider and loves exploring new places.

How to migrate asymmetric keys from CloudHSM to AWS KMS

Post Syndicated from Mani Manasa Mylavarapu original https://aws.amazon.com/blogs/security/how-to-migrate-asymmetric-keys-from-cloudhsm-to-aws-kms/

In June 2023, Amazon Web Services (AWS) introduced a new capability to AWS Key Management Service (AWS KMS): you can now import asymmetric key materials such as RSA or elliptic-curve cryptography (ECC) private keys for your signing workflow into AWS KMS. This means that you can move your asymmetric keys that are managed outside of AWS KMS—such as a hybrid (on-premises) environment, multi-cloud environment, and even AWS CloudHSM—and make them available through AWS KMS. Combined with the announcement on AWS KMS HSMs achieving FIPS 140-2 Security Level 3, you can make sure that your keys are secured and used in a manner that aligns to the cryptographic standards laid out by the U.S. National Institute of Standards and Technology (NIST).

In this post, we will show you how to migrate your asymmetric keys from CloudHSM to AWS KMS. This can help you simplify your key management strategy and take advantage of the robust authorization control of AWS KMS key policies.

Benefits of importing key materials into AWS KMS

In general, we recommend that you use a native KMS key because it provides the best security, durability, and availability compared to other key store options. AWS KMS FIPS-validated hardware security modules (HSMs) generate the key materials for KMS keys, and these key materials never leave the HSMs unencrypted. Operations that require use of your KMS key (for example, decryption of a data key or digital signature signing) must occur within the HSM.

However, depending on your organization’s requirements, you might need to bring your own key (BYOK) from outside. Importing your own key gives you direct control over the generation, lifecycle management, and durability of your keys. In addition, you have full control over the availability of your imported keys because you can set an expiration period or delete and reimport the keys at any time. You have greater control over the durability of your imported keys because you can maintain the original version of the keys elsewhere. If you need to generate and store copies of keys outside of AWS, these additional controls can help you meet your compliance requirements.

Solution overview

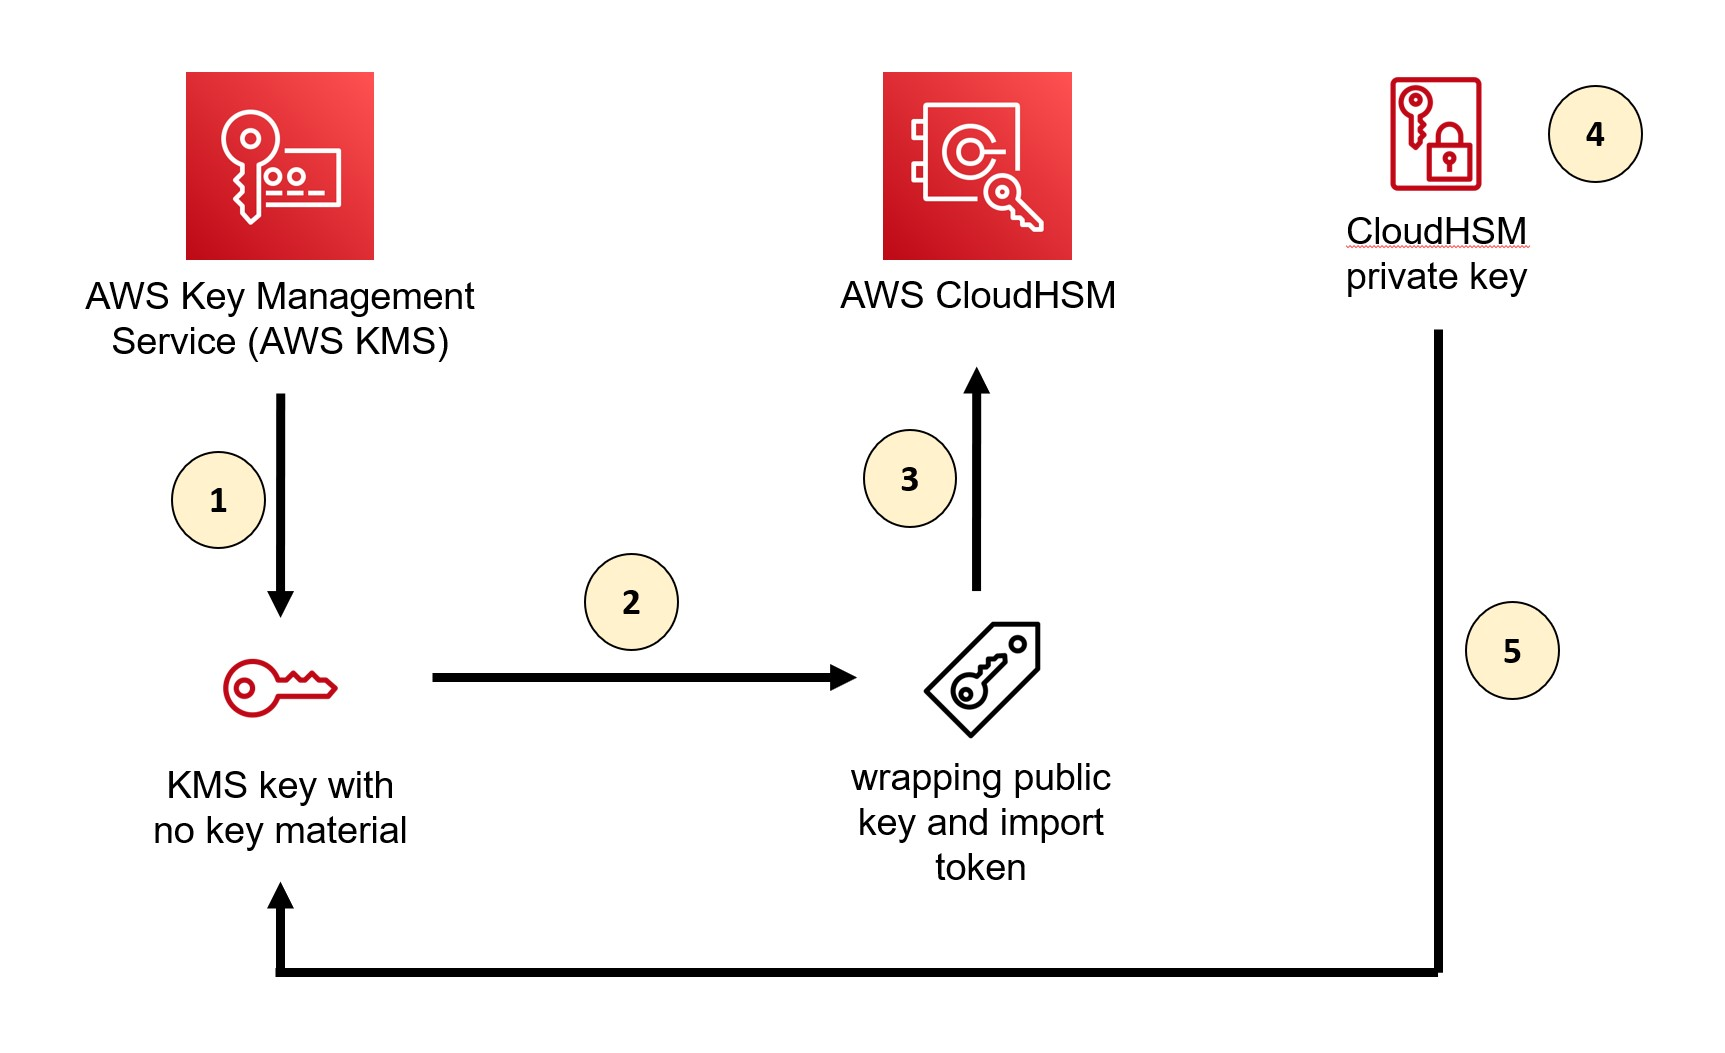
At a high level, our solution involves downloading the wrapping key from AWS KMS, using the CloudHSM Command Line Interface (CLI) to import a wrapping key to CloudHSM, wrapping the private key by using the wrapping key in CloudHSM, and uploading the wrapped private key to AWS KMS by using an import token. You can perform the same procedures by using other supported libraries, such as the PKCS #11 library or a JCE provider.

Figure 1: Overall architecture of the solution

Figure 1: Overall architecture of the solution

As shown in Figure 1, the solution involves the following steps:

  1. Create a KMS key without key material in AWS KMS
  2. Download the wrapping public key and import token from AWS KMS
  3. Import the wrapping key provided by AWS KMS into CloudHSM
  4. Wrap the private key inside CloudHSM with the imported wrapping public key from AWS KMS
  5. Import the wrapped private key to AWS KMS

For the walkthrough in this post, you will import into AWS KMS an ECC 256-bit private key (NIST P-256) that’s used for signing purpose from a CloudHSM cluster. When you import an asymmetric key into AWS KMS, you only need to import a private key. You don’t need to import a public key because AWS KMS can generate and retrieve a public key from the private key after the private key is imported.

Prerequisites

To follow along with this walkthrough, make sure that you have the following prerequisites in place:

  1. An active CloudHSM cluster with at least one active HSM and a valid crypto user credential.
  2. An Amazon Elastic Compute Cloud (Amazon EC2) instance with the CloudHSM Client SDK 5 installed and configured to connect to the CloudHSM cluster. For instructions on how to configure and connect the client instance, see Getting started with AWS CloudHSM.
  3. OpenSSL installed on your EC2 instance (we recommend version 3.0.0 or newer).

Step 1: Create a KMS key without key material in AWS KMS

The first step is to create a new KMS key. You can do this through the AWS KMS console or the AWS CLI, or by running the CreateKey API operation.

When you create your key, keep the following guidance in mind:

  • Set the key material origin to External so that no key material is created for this new key.
  • According to NIST SP 800-57 guidance and cryptography best practice, in general, you should use a single key for only one purpose (for example, if you use an RSA key for encryption, you shouldn’t also use that key for signing). Select the key usage that best suits your use case.
  • Make sure that the key spec match the algorithm specification of the key that you are trying to import from CloudHSM.
  • If you want to use the key in multiple AWS Regions (for example, to avoid the need for a cross-Region call to access the key), consider using a multi-Region key.

To create a KMS key using the AWS CLI

  • Run the following command:
    aws kms create-key --origin EXTERNAL --key-spec ECC_NIST_P256 --key-usage SIGN_VERIFY

Step 2: Download the wrapping public key and import token from AWS KMS

After you create the key, download the wrapping key and import token.

The wrapping key spec and the wrapping algorithm that you select depend on the key that you’re trying to import. AWS KMS supports several standard RSA wrapping algorithms and a two-step hybrid wrapping algorithm. CloudHSM supports both wrapping algorithms as well.

In general, an RSA wrapping algorithm (RSAES_OAEP_SHA_*) with a key spec of RSA_4096 should be sufficient for wrapping ECC private keys because it can wrap the key material completely. However, when importing RSA private keys, you will need to use the two-step hybrid wrapping algorithm (RSA_AES_KEY_WRAP_SHA_*) due to their large key size. The overall process is the same as what’s shown here, but the two-step hybrid wrapping algorithm requires that you encrypt your key material with an Advanced Encryption Standard (AES) symmetric key that you generate, and then encrypt the AES symmetric key with the RSA public wrapping key. Additionally, when you select the wrapping algorithm, you also have a choice between the SHA-1 or SHA-256 hashing algorithm. We recommend that you use the SHA-256 hashing algorithm whenever possible.

Note that each wrapping public key and import token set is valid for 24 hours. If you don’t use the set to import key material within 24 hours of downloading it, you must download a new set.

To download the wrapping public key and import token from AWS KMS

  1. Run the following command. Make sure to replace <KMS KeyID> with the key ID of the KMS key that you created in the previous step. The key ID is the last part of the key ARN after :key/ (for example, arn:aws:kms:us-east-1:<AWS Account ID>:key/<Key ID>). “ImportToken.b64” represents the wrapping token, and “WrappingPublicKey.b64” represents the import token.
    aws kms get-parameters-for-import \
    --key-id <KMS KeyID> \
    --wrapping-algorithm RSAES_OAEP_SHA_256 \
    --wrapping-key-spec RSA_4096 \
    --query "[ImportToken, PublicKey]" \
    --output text \
    | awk '{print $1 > "ImportToken.b64"; print $2 > "WrappingPublicKey.b64"}'

  2. Decode the base64 encoding.
    openssl enc -d -base64 -A -in WrappingPublicKey.b64 -out WrappingPublicKey.bin

To convert the wrapping public key from DER to PEM format

  • The key import pem command in CloudHSM CLI requires that the public key is in PEM format. AWS KMS outputs public keys in the DER format, so you must convert the wrapping public key to PEM format. To convert the public key to PEM format, run the following command:
    openssl rsa -pubin -in WrappingPublicKey.bin -inform DER -outform PEM -out WrappingPublicKey.pem

Step 3: Import the wrapping key provided by AWS KMS into CloudHSM

Now that you have created the KMS key and made the necessary preparations to import it, switch to CloudHSM to import the key.

To import the wrapping key

  1. Log in to your EC2 instance that has the CloudHSM CLI installed and run the following command to use it in an interactive mode:
    /opt/cloudhsm/bin/cloudhsm-cli interactive

  2. Log in with your crypto user credential. Make sure to replace <YourUserName> with your own information and supply your password when prompted.
    login --username <YourUserName> --role crypto-user

  3. Import the wrapping key and set the attribute allowing this key to be used for wrapping other keys.
    key import pem --path ./WrappingPublicKey.pem --label <kms-wrapping-key> --key-type-class rsa-public --attributes wrap=true

    You should see an output similar to the following:

    {
      "error_code": 0,
      "data": {
        "key": {
          "key-reference": "0x00000000002800c2",
          "key-info": {
            "key-owners": [
              {
                "username": "<YourUserName>",
                "key-coverage": "full"
              }
            ],
            "shared-users": [],
            "cluster-coverage": "full"
          },
          "attributes": {
            "key-type": "rsa",
            "label": "<kms-wrapping-key>",
            "id": "0x",
            "check-value": "0x5efd07",
            "class": "public-key",
            "encrypt": false,
            "decrypt": false,
            "token": true,
            "always-sensitive": false,
            "derive": false,
            "destroyable": true,
            "extractable": true,
            "local": false,
            "modifiable": true,
            "never-extractable": false,
            "private": true,
            "sensitive": false,
            "sign": false,
            "trusted": false,
            "unwrap": false,
            "verify": false,
            "wrap": true,
            "wrap-with-trusted": false,
            "key-length-bytes": 1024,
            "public-exponent": "0x010001",
            "modulus": "0xd7683010 … b6fc9df07",
            "modulus-size-bits": 4096
          }
        },
        "message": "Successfully imported key"
      }
    }

  4. From the output, note the value for the key label (<kms-wrapping-key> in this example) because you will need it for the next step.

Step 4: Wrap the private key inside CloudHSM with the imported wrapping public key from AWS KMS

Now that you have imported the wrapping key into CloudHSM, you can wrap the private key that you want to import to AWS KMS by using the wrapping key.

Important: Only the owner of a key—the crypto user who created the key—can wrap the key. In addition, the key that you want to wrap must have the extractable attribute set to true.

To wrap the private key

  1. Use the key wrap command in the CloudHSM CLI to wrap the private key that’s stored in CloudHSM. Make sure to replace the following placeholder values with your own information:
    • rsa-oaep specifies the wrapping algorithm.
    • --payload-filter is used to define the key that you want to wrap out of the HSM. You can use the key reference (for example, key-reference=0x00000000002800c2) or reference key attributes, such as the key label. In our example, we used the key label ec-priv-import-to-kms.
    • --wrapping-filter is used to define the key that you will use to wrap out the payload key. This should be the wrapping key that you imported previously from AWS KMS, which was labeled kms-wrapping-key in Step 3.3.
    • --hash-function defines the hash function used as part of the OAEP encryption. This should match the wrapping algorithm that you specified when you got the import parameters from AWS KMS. In our example, it should be SHA-256 because we selected RSAES_OAEP_SHA_256 as the wrapping algorithm previously.
    • --mgf defines the mask generation function used as part of the OAEP encryption. The mask hash function must match the signing mechanism hash function, which is SHA-256 in this example.
    • --path defines the path to the binary file where the wrapped key data will be saved. In this example, we name the file EncryptedECC_P256KeyMaterial.bin but you can specify a different name.
    key wrap rsa-oaep --payload-filter attr.label=ec-priv-import-to-kms --wrapping-filter attr.label=kms-wrapping-key --hash-function sha256 --mgf mgf1-sha256 --path EncryptedECC_P256KeyMaterial.bin

(Optional) To export the public key

  • You can also use the CloudHSM CLI to export the public key of your private key. You will use this key for testing later. Make sure to replace the placeholder values <ec-priv-import-to-kms> and <KeyName.pem> with your own information.
    key generate-file --encoding pem --path <KeyName.pem> --filter attr.label=<ec-priv-import-to-kms>

Step 5: Import the wrapped private key to AWS KMS

Now that you’ve wrapped the private key from CloudHSM, you can import it into AWS KMS.

Note that you have the option to set an expiration time for your imported key. After the expiration time passes, AWS KMS deletes your imported key automatically.

To import the wrapped private key to AWS KMS

  1. If you have been using the CLI or API, the import token is base64 encoded. You must decode the token from base64 to binary format before it can be used. You can use OpenSSL to do this.
    openssl enc -d -base64 -A -in ImportToken.b64 -out ImportToken.bin

  2. Run the following command to import the wrapped private key. Make sure to replace <KMS KeyID> with the key ID of the KMS key that you created in Step 1.
    aws kms import-key-material --key-id <KMS KeyID> \
    --encrypted-key-material fileb://EncryptedECC_P256KeyMaterial.bin \
    --import-token fileb://ImportToken.bin \
    --expiration-model KEY_MATERIAL_DOES_NOT_EXPIRE

Test whether your private key was imported successfully

The nature of asymmetric cryptography means that a digital signature produced by your private key should produce the same signature on the same message, regardless of the tool that you used to perform the signing operation. To verify that your imported private key functions the same in both CloudHSM and AWS KMS, you can perform a signing operation and compare the signature on CloudHSM and AWS KMS to make sure that they are the same.

Another way to check that your imported private key functions are the same in AWS KMS is to perform a signing operation and then verify the signature by using the corresponding public key that you exported from CloudHSM in Step 4. We will show you how to use this method to check that your private key was imported successfully.

To test that your private key was imported

  1. Create a simple message in a text file and encode it in base64.
    echo -n 'Testing My Imported Key!' | openssl base64 -out msg_base64.txt

  2. Perform the signing operation by using AWS KMS. Make sure to replace <YourImported KMS KeyID> with your own information.
    aws kms sign --key-id <YourImported KMS KeyID> --message fileb://msg_base64.txt --message-type RAW --signing-algorithm ECDSA_SHA_256

    The following shows the output of the signing operation.

    {
    "KeyId": "arn:aws:kms:us-east-1:111122223333:key/1234abcd-12ab-34cd-56ef-1234567890ab",
    "Signature": "EXAMPLEXsP11QVTkrSsab2CygcgtodDbSpd+j558B4qINpKIxwIhAMkKwd65mA3roo76ItuHiRsbwO9F0XMyuyKCKEXAMPLE",
    "SigningAlgorithm": "ECDSA_SHA_256"
    }

  3. Save the signature in a separate file called signature.sig and decode it from base64 to binary.
    openssl enc -d -base64 -in signature.sig -out signature.bin

  4. Verify the signature by using the public key that you exported from CloudHSM in Step 4.
    openssl dgst -sha256 -verify <KeyName.pem> -signature signature.bin msg_base64.txt

    If successful, you should see a message that says Verified OK.

Conclusion

In this post, you learned how to import an asymmetric key into AWS KMS from CloudHSM by using the CloudHSM CLI.

Although this post focused on migrating keys from CloudHSM, you can also follow the general directions to import your asymmetric key from elsewhere. When you import a private key, make sure that the imported key matches the key spec and the wrapping algorithm that you choose in AWS KMS.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Mani Manasa Mylavarapu

Mani Manasa Mylavarapu

Manasa is a Software Development Manager at AWS KMS. Manasa leads the development of custom key store features for both the CloudHSM Key Store and External Key Store. Beyond her professional role, Manasa enjoys playing board games and exploring the scenic hikes of Seattle.

Author

Kevin Lee

Kevin is a Senior Product Manager at AWS KMS. Kevin’s work interests include client-side encryption and key management strategy within a multi-tenant environment. Outside of work, Kevin enjoys occasional camping and snowboarding in the Pacific Northwest and playing video games.

Patrick Palmer

Patrick Palmer

Patrick is a Principal Security Specialist Solutions Architect. He helps customers around the world use AWS services in a secure manner, and specializes in cryptography. When not working, he enjoys spending time with his growing family and playing video games.

Combine transactional, streaming, and third-party data on Amazon Redshift for financial services

Post Syndicated from Satesh Sonti original https://aws.amazon.com/blogs/big-data/combine-transactional-streaming-and-third-party-data-on-amazon-redshift-for-financial-services/

Financial services customers are using data from different sources that originate at different frequencies, which includes real time, batch, and archived datasets. Additionally, they need streaming architectures to handle growing trade volumes, market volatility, and regulatory demands. The following are some of the key business use cases that highlight this need:

  • Trade reporting – Since the global financial crisis of 2007–2008, regulators have increased their demands and scrutiny on regulatory reporting. Regulators have placed an increased focus to both protect the consumer through transaction reporting (typically T+1, meaning 1 business day after the trade date) and increase transparency into markets via near-real-time trade reporting requirements.
  • Risk management – As capital markets become more complex and regulators launch new risk frameworks, such as Fundamental Review of the Trading Book (FRTB) and Basel III, financial institutions are looking to increase the frequency of calculations for overall market risk, liquidity risk, counter-party risk, and other risk measurements, and want to get as close to real-time calculations as possible.
  • Trade quality and optimization – In order to monitor and optimize trade quality, you need to continually evaluate market characteristics such as volume, direction, market depth, fill rate, and other benchmarks related to the completion of trades. Trade quality is not only related to broker performance, but is also a requirement from regulators, starting with MIFID II.

The challenge is to come up with a solution that can handle these disparate sources, varied frequencies, and low-latency consumption requirements. The solution should be scalable, cost-efficient, and straightforward to adopt and operate. Amazon Redshift features like streaming ingestion, Amazon Aurora zero-ETL integration, and data sharing with AWS Data Exchange enable near-real-time processing for trade reporting, risk management, and trade optimization.

In this post, we provide a solution architecture that describes how you can process data from three different types of sources—streaming, transactional, and third-party reference data—and aggregate them in Amazon Redshift for business intelligence (BI) reporting.

Solution overview

This solution architecture is created prioritizing a low-code/no-code approach with the following guiding principles:

  • Ease of use – It should be less complex to implement and operate with intuitive user interfaces
  • Scalable – You should be able to seamlessly increase and decrease capacity on demand
  • Native integration – Components should integrate without additional connectors or software
  • Cost-efficient – It should deliver balanced price/performance
  • Low maintenance – It should require less management and operational overhead

The following diagram illustrates the solution architecture and how these guiding principles were applied to the ingestion, aggregation, and reporting components.

Deploy the solution

You can use the following AWS CloudFormation template to deploy the solution.

Launch Cloudformation Stack

This stack creates the following resources and necessary permissions to integrate the services:

Ingestion

To ingest data, you use Amazon Redshift Streaming Ingestion to load streaming data from the Kinesis data stream. For transactional data, you use the Redshift zero-ETL integration with Amazon Aurora MySQL. For third-party reference data, you take advantage of AWS Data Exchange data shares. These capabilities allow you to quickly build scalable data pipelines because you can increase the capacity of Kinesis Data Streams shards, compute for zero-ETL sources and targets, and Redshift compute for data shares when your data grows. Redshift streaming ingestion and zero-ETL integration are low-code/no-code solutions that you can build with simple SQLs without investing significant time and money into developing complex custom code.

For the data used to create this solution, we partnered with FactSet, a leading financial data, analytics, and open technology provider. FactSet has several datasets available in the AWS Data Exchange marketplace, which we used for reference data. We also used FactSet’s market data solutions for historical and streaming market quotes and trades.

Processing

Data is processed in Amazon Redshift adhering to an extract, load, and transform (ELT) methodology. With virtually unlimited scale and workload isolation, ELT is more suited for cloud data warehouse solutions.

You use Redshift streaming ingestion for real-time ingestion of streaming quotes (bid/ask) from the Kinesis data stream directly into a streaming materialized view and process the data in the next step using PartiQL for parsing the data stream inputs. Note that streaming materialized views differs from regular materialized views in terms of how auto refresh works and the data management SQL commands used. Refer to Streaming ingestion considerations for details.

You use the zero-ETL Aurora integration for ingesting transactional data (trades) from OLTP sources. Refer to Working with zero-ETL integrations for currently supported sources. You can combine data from all these sources using views, and use stored procedures to implement business transformation rules like calculating weighted averages across sectors and exchanges.

Historical trade and quote data volumes are huge and often not queried frequently. You can use Amazon Redshift Spectrum to access this data in place without loading it into Amazon Redshift. You create external tables pointing to data in Amazon Simple Storage Service (Amazon S3) and query similarly to how you query any other local table in Amazon Redshift. Multiple Redshift data warehouses can concurrently query the same datasets in Amazon S3 without the need to make copies of the data for each data warehouse. This feature simplifies accessing external data without writing complex ETL processes and enhances the ease of use of the overall solution.

Let’s review a few sample queries used for analyzing quotes and trades. We use the following tables in the sample queries:

  • dt_hist_quote – Historical quotes data containing bid price and volume, ask price and volume, and exchanges and sectors. You should use relevant datasets in your organization that contain these data attributes.
  • dt_hist_trades – Historical trades data containing traded price, volume, sector, and exchange details. You should use relevant datasets in your organization that contain these data attributes.
  • factset_sector_map – Mapping between sectors and exchanges. You can obtain this from the FactSet Fundamentals ADX dataset.

Sample query for analyzing historical quotes

You can use the following query to find weighted average spreads on quotes:

select
date_dt :: date,
case
when exchange_name like 'Cboe%' then 'CBOE'
when (exchange_name) like 'NYSE%' then 'NYSE'
when (exchange_name) like 'New York Stock Exchange' then 'NYSE'
when (exchange_name) like 'Nasdaq%' then 'NASDAQ'
end as parent_exchange_name,
sector_name,
sum(spread * weight)/sum(weight) :: decimal (30,5) as weighted_average_spread
from
(
select date_dt,exchange_name,
factset_sector_desc sector_name,
((bid_price*bid_volume) + (ask_price*ask_volume))as weight,
((ask_price - bid_price)/ask_price) as spread
from
dt_hist_quotes a
join
fds_adx_fundamentals_db.ref_v2.factset_sector_map b
on(a.sector_code = b.factset_sector_code)
where ask_price <> 0 and bid_price <> 0
)
group by 1,2,3

Sample query for analyzing historical trades

You can use the following query to find $-volume on trades by detailed exchange, by sector, and by major exchange (NYSE and Nasdaq):

select
cast(date_dt as date) as date_dt,
case
when exchange_name like 'Cboe%' then 'CBOE'
when (exchange_name) like 'NYSE%' then 'NYSE'
when (exchange_name) like 'New York Stock Exchange' then 'NYSE'
when (exchange_name) like 'Nasdaq%' then 'NASDAQ'
end as parent_exchange_name,
factset_sector_desc sector_name,
sum((price * volume):: decimal(30,4)) total_transaction_amt
from
dt_hist_trades a
join
fds_adx_fundamentals_db.ref_v2.factset_sector_map b
on(a.sector_code = b.factset_sector_code)
group by 1,2,3

Reporting

You can use Amazon QuickSight and Amazon Managed Grafana for BI and real-time reporting, respectively. These services natively integrate with Amazon Redshift without the need to use additional connectors or software in between.

You can run a direct query from QuickSight for BI reporting and dashboards. With QuickSight, you can also locally store data in the SPICE cache with auto refresh for low latency. Refer to Authorizing connections from Amazon QuickSight to Amazon Redshift clusters for comprehensive details on how to integrate QuickSight with Amazon Redshift.

You can use Amazon Managed Grafana for near-real-time trade dashboards that are refreshed every few seconds. The real-time dashboards for monitoring the trade ingestion latencies are created using Grafana and the data is sourced from system views in Amazon Redshift. Refer to Using the Amazon Redshift data source to learn about how to configure Amazon Redshift as a data source for Grafana.

The users who interact with regulatory reporting systems include analysts, risk managers, operators, and other personas that support business and technology operations. Apart from generating regulatory reports, these teams require visibility into the health of the reporting systems.

Historical quotes analysis

In this section, we explore some examples of historical quotes analysis from the Amazon QuickSight dashboard.

Weighted average spread by sectors

The following chart shows the daily aggregation by sector of the weighted average bid-ask spreads of all the individual trades on NASDAQ and NYSE for 3 months. To calculate the average daily spread, each spread is weighted by the sum of the bid and the ask dollar volume. The query to generate this chart processes 103 billion of data points in total, joins each trade with the sector reference table, and runs in less than 10 seconds.

Weighted average spread by exchanges

The following chart shows the daily aggregation of the weighted average bid-ask spreads of all the individual trades on NASDAQ and NYSE for 3 months. The calculation methodology and query performance metrics are similar to those of the preceding chart.

Historical trades analysis

In this section, we explore some examples of historical trades analysis from the Amazon QuickSight dashboard.

Trade volumes by sector

The following chart shows the daily aggregation by sector of all the individual trades on NASDAQ and NYSE for 3 months. The query to generate this chart processes 3.6 billion of trades in total, joins each trade with the sector reference table, and runs in under 5 seconds.

Trade volumes for major exchanges

The following chart shows the daily aggregation by exchange group of all the individual trades for 3 months. The query to generate this chart has similar performance metrics as the preceding chart.

Real-time dashboards

Monitoring and observability is an important requirement for any critical business application such as trade reporting, risk management, and trade management systems. Apart from system-level metrics, it’s also important to monitor key performance indicators in real time so that operators can be alerted and respond as soon as possible to business-impacting events. For this demonstration, we have built dashboards in Grafana that monitor the delay of quote and trade data from the Kinesis data stream and Aurora, respectively.

The quote ingestion delay dashboard shows the amount of time it takes for each quote record to be ingested from the data stream and be available for querying in Amazon Redshift.

The trade ingestion delay dashboard shows the amount of time it takes for a transaction in Aurora to become available in Amazon Redshift for querying.

Clean up

To clean up your resources, delete the stack you deployed using AWS CloudFormation. For instructions, refer to Deleting a stack on the AWS CloudFormation console.

Conclusion

Increasing volumes of trading activity, more complex risk management, and enhanced regulatory requirements are leading capital markets firms to embrace real-time and near-real-time data processing, even in mid- and back-office platforms where end of day and overnight processing was the standard. In this post, we demonstrated how you can use Amazon Redshift capabilities for ease of use, low maintenance, and cost-efficiency. We also discussed cross-service integrations to ingest streaming market data, process updates from OLTP databases, and use third-party reference data without having to perform complex and expensive ETL or ELT processing before making the data available for analysis and reporting.

Please reach out to us if you need any guidance in implementing this solution. Refer to Real-time analytics with Amazon Redshift streaming ingestion, Getting started guide for near-real time operational analytics using Amazon Aurora zero-ETL integration with Amazon Redshift, and Working with AWS Data Exchange data shares as a producer for more information.


About the Authors

Satesh Sonti is a Sr. Analytics Specialist Solutions Architect based out of Atlanta, specialized in building enterprise data platforms, data warehousing, and analytics solutions. He has over 18 years of experience in building data assets and leading complex data platform programs for banking and insurance clients across the globe.

Alket Memushaj works as a Principal Architect in the Financial Services Market Development team at AWS. Alket is responsible for technical strategy for capital markets, working with partners and customers to deploy applications across the trade lifecycle to the AWS Cloud, including market connectivity, trading systems, and pre- and post-trade analytics and research platforms.

Ruben Falk is a Capital Markets Specialist focused on AI and data & analytics. Ruben consults with capital markets participants on modern data architecture and systematic investment processes. He joined AWS from S&P Global Market Intelligence where he was Global Head of Investment Management Solutions.

Jeff Wilson is a World-wide Go-to-market Specialist with 15 years of experience working with analytic platforms. His current focus is sharing the benefits of using Amazon Redshift, Amazon’s native cloud data warehouse. Jeff is based in Florida and has been with AWS since 2019.

Data masking and granular access control using Amazon Macie and AWS Lake Formation

Post Syndicated from Iris Ferreira original https://aws.amazon.com/blogs/security/data-masking-and-granular-access-control-using-amazon-macie-and-aws-lake-formation/

Companies have been collecting user data to offer new products, recommend options more relevant to the user’s profile, or, in the case of financial institutions, to be able to facilitate access to higher credit lines or lower interest rates. However, personal data is sensitive as its use enables identification of the person using a specific system or application and in the wrong hands, this data might be used in unauthorized ways. Governments and organizations have created laws and regulations, such as General Data Protection Regulation (GDPR) in the EU, General Data Protection Law (LGPD) in Brazil, and technical guidance such as the Cloud Computing Implementation Guide published by the Association of Banks in Singapore (ABS), that specify what constitutes sensitive data and how companies should manage it. A common requirement is to ensure that consent is obtained for collection and use of personal data and that any data collected is anonymized to protect consumers from data breach risks.

In this blog post, we walk you through a proposed architecture that implements data anonymization by using granular access controls according to well-defined rules. It covers a scenario where a user might not have read access to data, but an application does. A common use case for this scenario is a data scientist working with sensitive data to train machine learning models. The training algorithm would have access to the data, but the data scientist would not. This approach helps reduce the risk of data leakage while enabling innovation using data.

Prerequisites

To implement the proposed solution, you must have an active AWS account and AWS Identity and Access Management (IAM) permissions to use the following services:

Note: If there’s a pre-existing Lake Formation configuration, there might be permission issues when testing this solution. We suggest that you test this solution on a development account that doesn’t yet have Lake Formation active. If you don’t have access to a development account, see more details about the permissions required on your role in the Lake Formation documentation.

You must give permission for AWS DMS to create the necessary resources, such as the EC2 instance where you will run DMS tasks. If you have ever worked with DMS, this permission should already exist. Otherwise, you can use CloudFormation to create the necessary roles to deploy the solution. To see if permission already exists, open the AWS Management Console and go to IAM, select Roles, and see if there is a role called dms-vpc-role. If not, you must create the role during deployment.

We use the Faker library to create dummy data consisting of the following tables:

  • Customer
  • Bank
  • Card

Solution overview

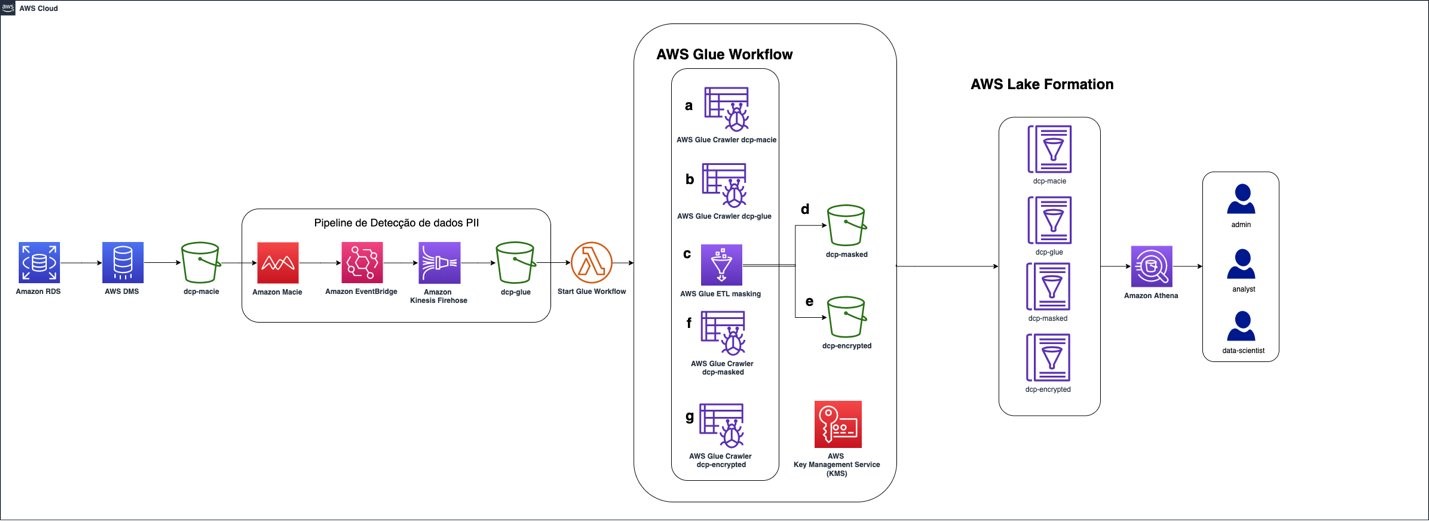
This architecture allows multiple data sources to send information to the data lake environment on AWS, where Amazon S3 is the central data store. After the data is stored in an S3 bucket, Macie analyzes the objects and identifies sensitive data using machine learning (ML) and pattern matching. AWS Glue then uses the information to run a workflow to anonymize the data.

Figure 1: Solution architecture for data ingestion and identification of PII

Figure 1: Solution architecture for data ingestion and identification of PII

We will describe two techniques used in the process: data masking and data encryption. After the workflow runs, the data is stored in a separate S3 bucket. This hierarchy of buckets is used to segregate access to data for different user personas.

Figure 1 depicts the solution architecture:

  1. The data source in the solution is an Amazon RDS database. Data can be stored in a database on an EC2 instance, in an on-premises server, or even deployed in a different cloud provider.
  2. AWS DMS uses full load, which allows data migration from the source (an Amazon RDS database) into the target S3 bucket — dcp-macie — as a one-time migration. New objects uploaded to the S3 bucket are automatically encrypted using server-side encryption (SSE-S3).
  3. A personally identifiable information (PII) detection pipeline is invoked after the new Amazon S3 objects are uploaded. Macie analyzes the objects and identifies values that are sensitive. Users can manually identify which fields and values within the files should be classified as sensitive or use the Macie automated sensitive data discovery capabilities.
  4. The sensitive values identified by Macie are sent to EventBridge, invoking Kinesis Data Firehose to store them in the dcp-glue S3 bucket. AWS Glue uses this data to know which fields to mask or encrypt using an encryption key stored in AWS KMS.
    1. Using EventBridge enables an event-based architecture. EventBridge is used as a bridge between Macie and Kinesis Data Firehose, integrating these services.
    2. Kinesis Data Firehose supports data buffering mitigating the risk of information loss when sent by Macie while reducing the overall cost of storing data in Amazon S3. It also allows data to be sent to other locations, such as Amazon Redshift or Splunk, making it available to be analyzed by other products.
  5. At the end of this step, Amazon S3 is invoked from a Lambda function that starts the AWS Glue workflow, which masks and encrypts the identified data.
    1. AWS Glue starts a crawler on the S3 bucket dcp-macie (a) and the bucket dcp-glue (b) to populate two tables, respectively, created as part of the AWS Glue service.
    2. After that, a Python script is run (c), querying the data in these tables. It uses this information to mask and encrypt the data and then store it in the prefixes dcp-masked (d) and dcp-encrypted (e) in the bucket dcp-athena.
    3. The last step in the workflow is to perform a crawler for each of these prefixes (f) and (g) by creating their respective tables in the AWS Glue Data Catalog.
  6. To enable fine-grained access to data, Lake Formation maps permissions to the tags you have configured. The implementation of this part is described further in this post.
  7. Athena can be used to query the data. Other tools, such as Amazon Redshift or Amazon Quicksight can also be used, as well as third-party tools.

If a user lacks permission to view sensitive data but needs to access it for machine learning model training purposes, AWS KMS can be used. The AWS KMS service manages the encryption keys that are used for data masking and to give access to the training algorithms. Users can see the masked data, but the algorithms can use the data in its original form to train the machine learning models.

This solution uses three personas:

secure-lf-admin: Data lake administrator. Responsible for configuring the data lake and assigning permissions to data administrators.
secure-lf-business-analyst: Business analyst. No access to certain confidential information.
secure-lf-data-scientist: Data scientist. No access to certain confidential information.

Solution implementation

To facilitate implementation, we created a CloudFormation template. The model and other artifacts produced can be found in this GitHub repository. You can use the CloudFormation dashboard to review the output of all the deployed features.

Choose the following Launch Stack button to deploy the CloudFormation template.

Select this image to open a link that starts building the CloudFormation stack

Deploy the CloudFormation template

To deploy the CloudFormation template and create the resources in your AWS account, follow the steps below.

  1. After signing in to the AWS account, deploy the CloudFormation template. On the Create stack window, choose Next.
    Figure 2: CloudFormation create stack screen

    Figure 2: CloudFormation create stack screen

  2. In the following section, enter a name for the stack. Enter a password in the TestUserPassword field for Lake Formation personas to use to sign in to the console. When finished filling in the fields, choose Next.
  3. On the next screen, review the selected options and choose Next.
  4. In the last section, review the information and select I acknowledge that AWS CloudFormation might create IAM resources with custom names. Choose Create Stack.
    Figure 3: List of parameters and values in the CloudFormation stack

    Figure 3: List of parameters and values in the CloudFormation stack

  5. Wait until the stack status changes to CREATE_COMPLETE.

The deployment process should take approximately 15 minutes to finish.

Run an AWS DMS task

To extract the data from the Amazon RDS instance, you must run an AWS DMS task. This makes the data available to Macie in an S3 bucket in Parquet format.

  1. Open the AWS DMS console.
  2. On the navigation bar, for the Migrate data option, select Database migration tasks.
  3. Select the task with the name rdstos3task.
  4. Choose Actions.
  5. Choose Restart/Resume. The loading process should take around 1 minute.

When the status changes to Load Complete, you will be able to see the migrated data in the target bucket (dcp-macie-<AWS_REGION>-<ACCOUNT_ID>) in the dataset folder. Within each prefix there will be a parquet file that follows the naming pattern: LOAD00000001.parquet. After this step, use Macie to scan the data for sensitive information in the files.

Run a classification job with Macie 

You must create a data classification job before you can evaluate the contents of the bucket. The job you create will run and evaluate the full contents of your S3 bucket to determine the files stored in the bucket contain PII. This job uses the managed identifiers available in Macie and a custom identifier.

  1. Open the Macie Console, on the navigation bar, select Jobs.
  2. Choose Create job.
  3. Select the S3 bucket dcp-macie-<AWS_REGION>-<ACCOUNT_ID> containing the output of the AWS DMS task. Choose Next to continue.
  4. On the Review Bucket page, verify the selected bucket is dcp-macie-<AWS_REGION>-<ACCOUNT_ID>, and then choose Next.
  5. In Refine the scope, create a new job with the following scope:
    1. Sensitive data Discovery options: One-time job (for demonstration purposes, this will be a single discovery job. For production environments, we recommend selecting the Scheduled job option, so Macie can analyze objects following a scheduled).
    2. Sampling Depth: 100 percent.
    3. Leave the other settings at their default values.
  6. On Managed data identifiers options, select All so Macie can use all managed data identifiers. This enables a set of built-in criteria to detect all identified types of sensitive data. Choose Next.
  7. On the Custom data identifiers option, select account_number, and then choose Next. With the custom identifier, you can create custom business logic to look for certain patterns in files stored in Amazon S3. In this example, the task generates a discovery job for files that contain data with the following regular expression format XYZ- followed by numbers, which is the default format of the false account_number generated in the dataset. The logic used for creating this custom data identifier is included in the CloudFormation template file.
  8. On the Select allow lists, choose Next to continue.
  9. Enter a name and description for the job.
  10. Choose Next to continue.
  11. On Review and create step, check the details of the job you created and choose Submit.
    Figure 4: List of Macie findings detected by the solution

    Figure 4: List of Macie findings detected by the solution

The amount of data being scanned directly influences how long the job takes to run. You can choose the Update button at the top of the screen, as shown in Figure 4, to see the updated status of the job. This job, based on the size of the test dataset, will take about 10 minutes to complete.

Run the AWS Glue data transformation pipeline

After the Macie job is finished, the discovery results are ingested into the bucket dcp-glue-<AWS_REGION>-<ACCOUNT_ID>, invoking the AWS Glue step of the workflow (dcp-Workflow), which should take approximately 11 minutes to complete.

To check the workflow progress:

  1. Open the AWS Glue console and on navigation bar, select Workflows (orchestration).
  2. Next, choose dcp-workflow.
  3. Next, select History to see the past runs of the dcp-workflow.

The AWS Glue job, which is launched as part of the workflow (dcp-workflow), reads the Macie findings to know the exact location of sensitive data. For example, in the customer table are name and birthdate. In the bank table are account_number, iban, and bban. And in the card table are card_number, card_expiration, and card_security_code. After this data is found, the job masks and encrypts the information.

Text encryption is done using an AWS KMS key. Here is the code snippet that provides this functionality:

def encrypt_rows(r):
    encrypted_entities = columns_to_be_masked_and_encrypted
    try:
        for entity in encrypted_entities:
            if entity in table_columns:
                encrypted_entity = get_kms_encryption(r[entity])
                r[entity + '_encrypted'] = encrypted_entity.decode("utf-8")
                del r[entity]
    except:
        print ("DEBUG:",sys.exc_info())
    return r

def get_kms_encryption(row):
    # Create a KMS client
    session = boto3.session.Session()
    client = session.client(service_name='kms',region_name=region_name)
   
    try:
        encryption_result = client.encrypt(KeyId=key_id, Plaintext=row)
        blob = encryption_result['CiphertextBlob']
        encrypted_row = base64.b64encode(blob)       
        return encrypted_row
       
    except:
        return 'Error on get_kms_encryption function'

If your application requires access to the unencrypted text, and because access to the AWS KMS encryption key exists, you can use the following excerpt example to access the information:

client.decrypt(CiphertextBlob=base64.b64decode(data_encrypted))
print(decrypted['Plaintext'])

After performing all the above steps, the datasets are fully anonymized with tables created in Data Catalog and data stored in the respective S3 buckets. These are the buckets where fine-grained access controls are applied through Lake Formation:

  • Masked data — s3://dcp-athena-<AWS_REGION>-<ACCOUNT_ID>/masked/
  • Encrypted data — s3://dcp-athena-<AWS_REGION>-<ACCOUNT_ID>/encrypted/

Now that the tables are defined, you refine the permissions using Lake Formation.

Enable Lake Formation fine-grained access

After the data is processed and stored, you use Lake Formation to define and enforce fine-grained access permissions and provide secure access to data analysts and data scientists.

To enable fine-grained access, you first add a user (secure-lf-admin) to Lake Formation:

  1. In the Lake Formation console, clear Add myself and select Add other AWS users or roles.
  2. From the drop-down menu, select secure-lf-admin.
  3. Choose Get started.
    Figure 5: Lake Formation deployment process

    Figure 5: Lake Formation deployment process

Grant access to different personas

Before you grant permissions to different user personas, you must register Amazon S3 locations in Lake Formation so that the personas can access the data. All buckets have been created with the following pattern <prefix>-<bucket_name>-<aws_region>-<account_id>, where <prefix> matches the prefix you selected when you deployed the Cloudformation template and <aws_region> corresponds to the selected AWS Region (for example, ap-southeast-1), and <account_id> is the 12 numbers that match your AWS account (for example, 123456789012). For ease of reading, we left only the initial part of the bucket name in the following instructions.

  1. In the Lake Formation console, on the navigation bar, on the Register and ingest option, select Data Lake locations.
  2. Choose Register location.
  3. Select the dcp-glue bucket and choose Register Location.
  4. Repeat for the dcp-macie/dataset, dcp-athena/masked, and dcp-athena/encrypted prefixes.
    Figure 6: Amazon S3 locations registered in the solution

    Figure 6: Amazon S3 locations registered in the solution

You’re now ready to grant access to different users.

Granting per-user granular access

After successfully deploying the AWS services described in the CloudFormation template, you must configure access to resources that are part of the proposed solution.

Grant read-only accesses to all tables for secure-lf-admin

Before proceeding you must sign in as the secure-lf-admin user. To do this, sign out from the AWS console and sign in again using the secure-lf-admin credential and password that you set in the CloudFormation template.

Now that you’re signed in as the user who administers the data lake, you can grant read-only access to all tables in the dataset database to the secure-lf-admin user.

  1. In the Permissions section, select Data Lake permissions, and then choose Grant.
  2. Select IAM users and roles.
  3. Select the secure-lf-admin user.
  4. Under LF-Tags or catalog resources, select Named data catalog resources.
  5. Select the database dataset.
  6. For Tables, select All tables.
  7. In the Table permissions section, select Alter and Super.
  8. Under Grantable permissions, select Alter and Super.
  9. Choose Grant.

You can confirm your user permissions on the Data Lake permissions page.

Create tags to grant access

Return to the Lake Formation console to define tag-based access control for users. You can assign policy tags to Data Catalog resources (databases, tables, and columns) to control access to this type of resources. Only users who receive the corresponding Lake Formation tag (and those who receive access with the resource method named) can access the resources.

  1. Open the Lake Formation console, then on the navigation bar, under Permissions, select LF-tags.
  2. Choose Add LF Tag. In the dialog box Add LF-tag, for Key, enter data, and for Values, enter mask. Choose Add, and then choose Add LF-Tag.
  3. Follow the same steps to add a second tag. For Key, enter segment, and for Values enter campaign.

Assign tags to users and databases

Now grant read-only access to the masked data to the secure-lf-data-scientist user.

  1. In the Lake Formation console, on the navigation bar, under Permissions, select Data Lake permissions. 
  2. Choose Grant.
  3. Under IAM users and roles, select secure-lf-data-scientist as the user.
  4. In the LF-Tags or catalog resources section, select Resources matched by LF-Tags and choose add LF-Tag. For Key, enter data and for Values, enter mask.
    Figure 7: Creating resource tags for Lake Formation

    Figure 7: Creating resource tags for Lake Formation

  5. In the section Database permissions, in the Database permissions part and in Grantable permissions, select Describe.
  6. In the section Table permissions, in the Table permissions part and in Grantable permissions, select Select.
  7. Choose Grant.
    Figure 8: Database and table permissions granted

    Figure 8: Database and table permissions granted

To complete the process and give the secure-lf-data-scientist user access to the dataset_masked database, you must assign the tag you created to the database.

  1. On the navigation bar, under Data Catalog, select Databases.
  2. Select dataset_masked and select Actions. From the drop-down menu, select Edit LF-Tags.
  3. In the section Edit LF-Tags: dataset_masked, choose Assign new LF-Tag. For Key, enter data, and for Values, enter mask. Choose Save.

Grant read-only accesses to secure-lf-business-analyst

Now grant the secure-lf-business-analyst user read-only access to certain encrypted columns using column-based permissions.

  1. In the Lake Formation console, under Data Catalog, select Databases.
  2. Select the database dataset_encrypted and then select Actions. From the drop-down menu, choose Grant.
  3. Select IAM users and roles.
  4. Choose secure-lf-business-analyst.
  5. In the LF-Tags or catalog resources section, select Named data catalog resources.
  6. In the Database permissions section, in the Database permissions section and in Grantable permissions, select Describe and Alter.
  7. Choose Grant.

Now give the secure-lf-business-analyst user access to the Customer table, except for the username column.

  1. In the Lake Formation console, under Data Catalog, select Databases.
  2. Select the database dataset_encrypted and then, choose View tables.
  3. From the Actions option in the drop-down menu, select Grant.
  4. Select IAM users and roles.
  5. Select secure-lf-business-analyst.
  6. In the LF-Tags or catalog resources part, select Named data catalog resources.
  7. In the Database section, leave the dataset_encrypted selected.
  8. In the tables section, select the customer table.
  9. In the Table permission section, in the Table permission section and in Grantable permissions, choose Select.
  10. In the Data Permissions section, select Column-based access.
  11. Select Include columns and select the id, username, mail, and gender columns, which are the data-less columns encrypted for the secure-lf-business-analyst user to have access to.
  12. Choose Grant.
    Figure 9: Granting access to secure-lf-business-analyst user in the Customer table

    Figure 9: Granting access to secure-lf-business-analyst user in the Customer table

Now give the secure-lf-business-analyst user access to the table Card, only for columns that do not contain PII information.

  1. In the Lake Formation console, under Data Catalog, choose Databases.
  2. Select the database dataset_encrypted and choose View tables.
  3. Select the table Card.
  4. In the Schema section, choose Edit schema.
  5. Select the cred_card_provider column, which is the column that has no PII data.
  6. Choose Edit tags.
  7. Choose Assign new LF-Tag.
  8. For Assigned keys, enter segment and for Values, enter mask.
    Figure 10: Editing tags in Lake Formation tables

    Figure 10: Editing tags in Lake Formation tables

  9. Choose Save, and then choose Save as new version.

In this step you add the segment tag in the column cred_card_provider to the card table. For the user secure-lf-business-analyst to have access, you need to configure this tag for the user.

  1. In the Lake Formation console, under Permissions, select Data Lake permissions.
  2. Choose Grant.
  3. Under IAM users and roles, select secure-lf-business-analyst as the user.
  4. In the LF-Tags or catalog resources section, select Resources matched by LF-Tags, and choose add LF-tag and for as Key enter segment and for Values, enter campaign.
    Figure 11: Configure tag-based access for user secure-lf-business-analyst

    Figure 11: Configure tag-based access for user secure-lf-business-analyst

  5. In the Database permissions section, in the Database permissions part and in Grantable permissions, select Describe from both options.
  6. In the Table permission section, in the Table permission part as well as in Grantable permissions, choose Select.
  7. Choose Grant.

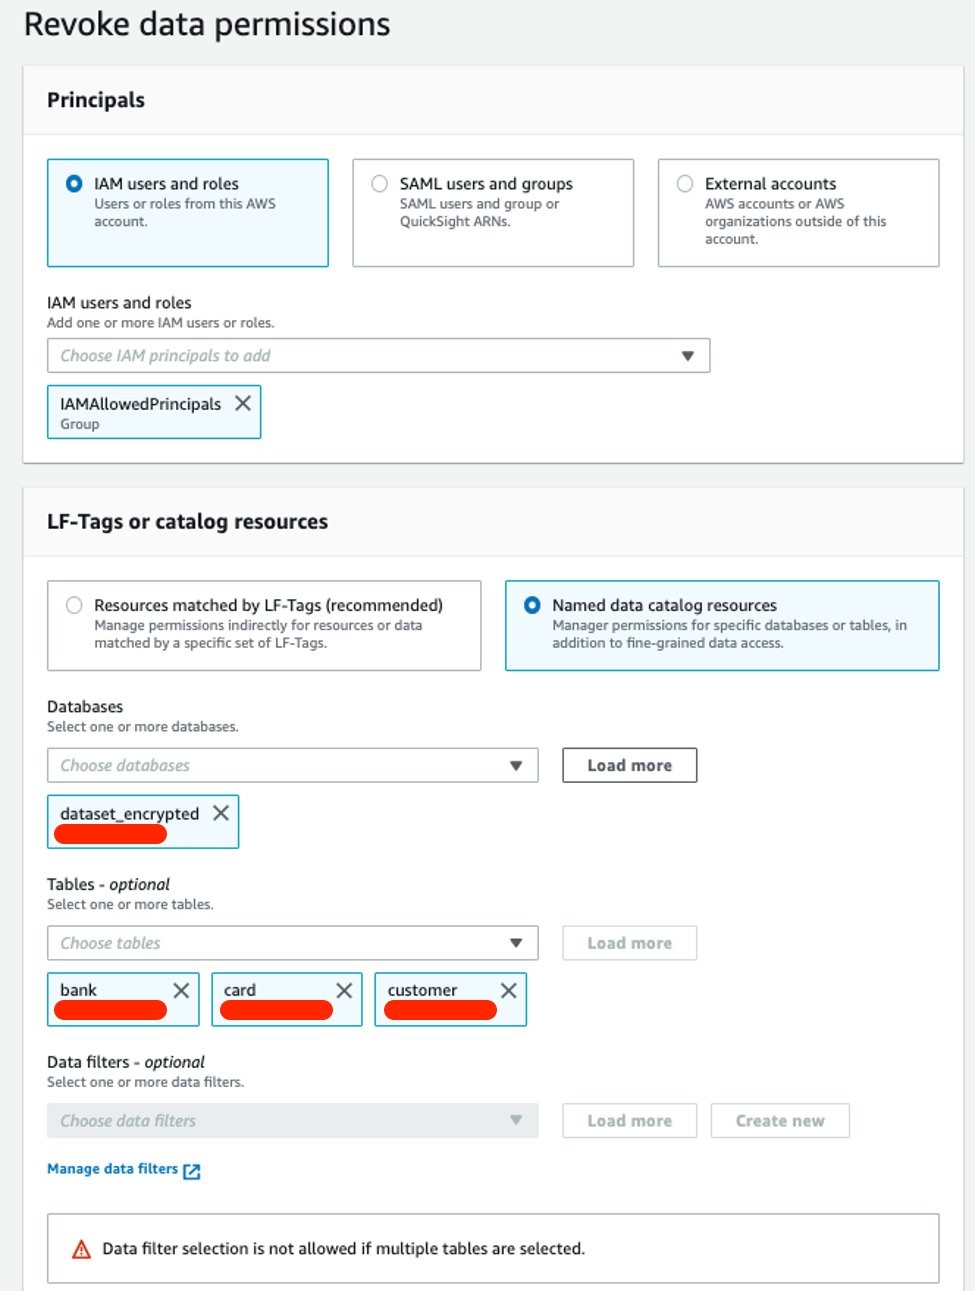
The next step is to revoke Super access to the IAMAllowedPrincipals group.

The IAMAllowedPrincipals group includes all IAM users and roles that are allowed access to Data Catalog resources using IAM policies. The Super permission allows a principal to perform all operations supported by Lake Formation on the database or table on which it is granted. These settings provide access to Data Catalog resources and Amazon S3 locations controlled exclusively by IAM policies. Therefore, the individual permissions configured by Lake Formation are not considered, so you will remove the concessions already configured by the IAMAllowedPrincipals group, leaving only the Lake Formation settings.

  1. In the Databases menu, select the database dataset, and then select Actions. From the drop-down menu, select Revoke.
  2. In the Principals section, select IAM users and roles, and then select the IAMAllowedPrincipals group as the user.
  3. Under LF-Tags or catalog resources, select Named data catalog resources.
  4. In the Database section, leave the dataset option selected.
  5. Under Tables, select the following tables: bank, card, and customer.
  6. In the Table permissions section, select Super.
  7. Choose Revoke.

Repeat the same steps for the dataset_encrypted and dataset_masked databases.

Figure 12: Revoke SUPER access to the IAMAllowedPrincipals group

Figure 12: Revoke SUPER access to the IAMAllowedPrincipals group

You can confirm all user permissions on the Data Permissions page.

Querying the data lake using Athena with different personas

To validate the permissions of different personas, you use Athena to query the Amazon S3 data lake.

Ensure the query result location has been created as part of the CloudFormation stack (secure-athena-query-<ACCOUNT_ID>-<AWS_REGION>).

  1. Sign in to the Athena console with secure-lf-admin (use the password value for TestUserPassword from the CloudFormation stack) and verify that you are in the AWS Region used in the query result location.
  2. On the navigation bar, choose Query editor.
  3. Choose Setting to set up a query result location in Amazon S3, and then choose Browse S3 and select the bucket secure-athena-query-<ACCOUNT_ID>-<AWS_REGION>.
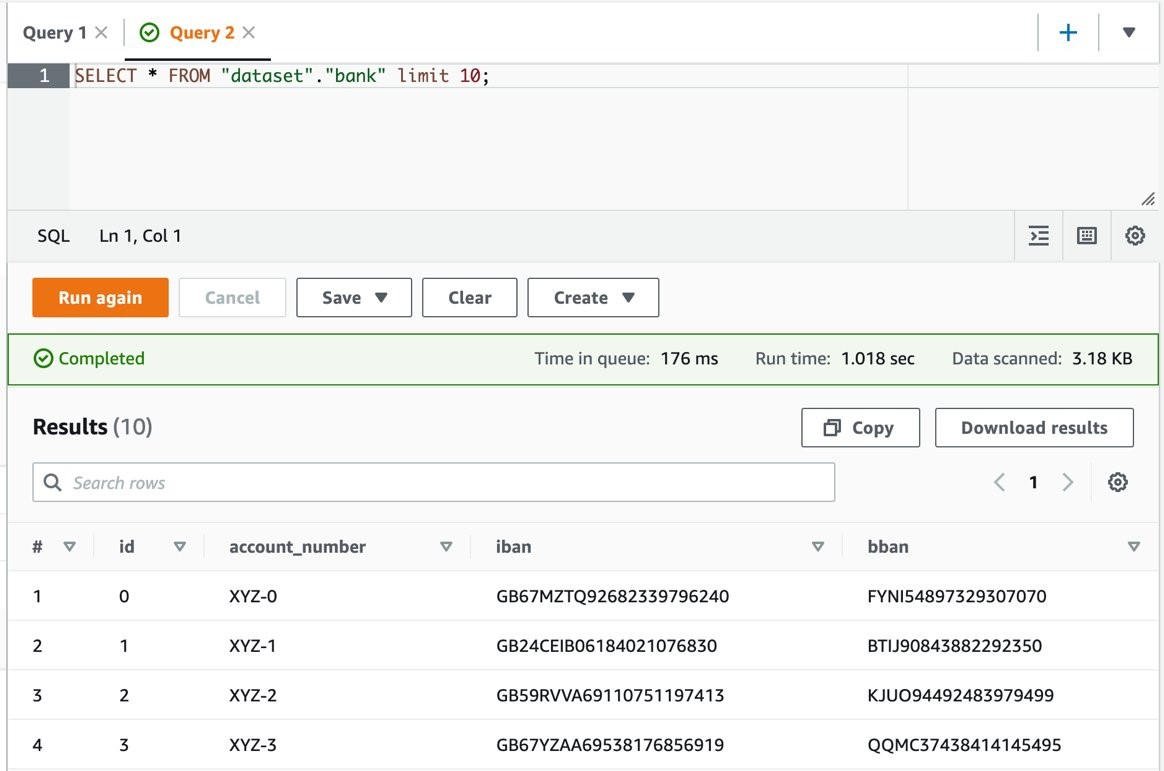
  4. Run a SELECT query on the dataset.
    SELECT * FROM "dataset"."bank" limit 10;

The secure-lf-admin user should see all tables in the dataset database and dcp. As for the banks dataset_encrypted and dataset_masked, the user should not have access to the tables.

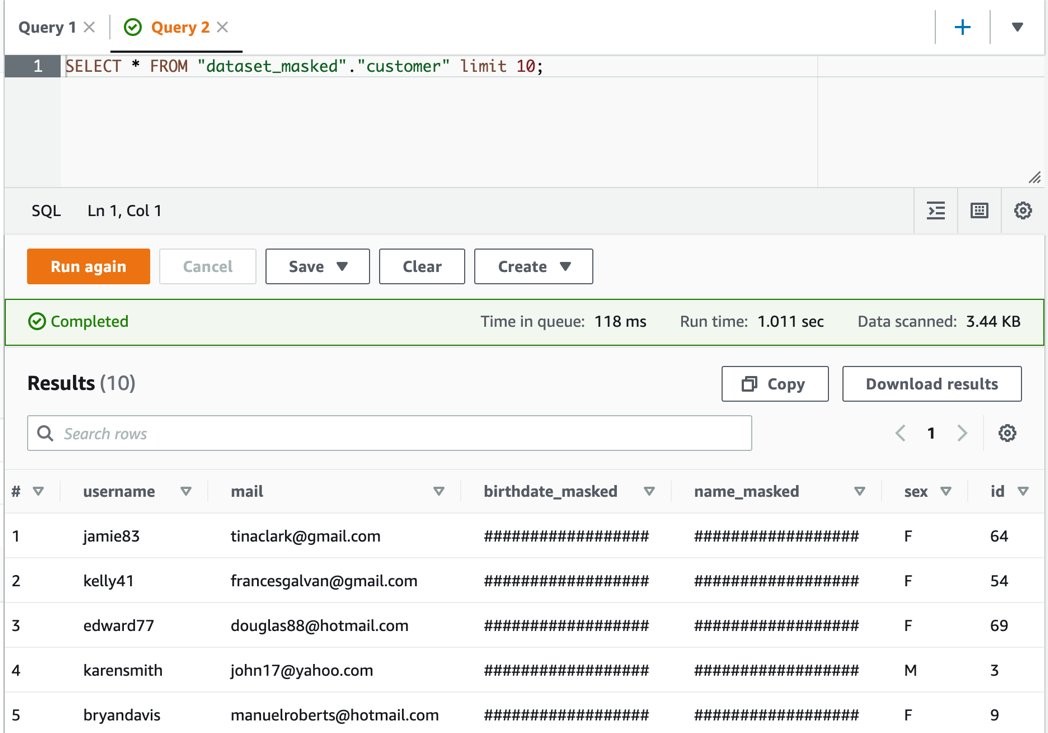
Figure 13: Athena console with query results in clear text

Figure 13: Athena console with query results in clear text

Finally, validate the secure-lf-data-scientist permissions.

  1. Sign in to the Athena console with secure-lf-data-scientist (use the password value for TestUserPassword from the CloudFormation stack) and verify that you are in the correct Region.
  2. Run the following query:
    SELECT * FROM “dataset_masked”.”bank” limit 10;

The user secure-lf-data-scientist will only be able to view all the columns in the database dataset_masked.

Figure 14: Athena query results with masked data

Figure 14: Athena query results with masked data

Now, validate the secure-lf-business-analyst user permissions.

  1. Sign in to the Athena console as secure-lf-business-analyst (use the password value for TestUserPassword from the CloudFormation stack) and verify that you are in the correct Region.
  2. Run a SELECT query on the dataset.
    SELECT * FROM “dataset_encrypted”.”card” limit 10;

    Figure 15: Validating secure-lf-business-analyst user permissions to query data

    Figure 15: Validating secure-lf-business-analyst user permissions to query data

The user secure-lf-business-analyst should only be able to view the card and customer tables of the dataset_encrypted database. In the table card, you will only have access to the cred_card_provider column and in the table Customer, you will have access only in the username, mail, and sex columns, as previously configured in Lake Formation.

Cleaning up the environment

After testing the solution, remove the resources you created to avoid unnecessary expenses.

  1. Open the Amazon S3 console.
  2. Navigate to each of the following buckets and delete all the objects within:
    1. dcp-assets-<AWS_REGION>-<ACCOUNT_ID>
    2. dcp-athena-<AWS_REGION>-<ACCOUNT_ID>
    3. dcp-glue-<AWS_REGION>-<ACCOUNT_ID>
    4. dcp-macie-<AWS_REGION>-<ACCOUNT_ID>
  3. Open the CloudFormation console.
  4. Select the Stacks option from the navigation bar.
  5. Select the stack that you created in Deploy the CloudFormation Template.
  6. Choose Delete, and then choose Delete Stack in the pop-up window.
  7. If you also want to delete the bucket that was created, go to Amazon S3 and delete it from the console or by using the AWS CLI.
  8. To remove the settings made in Lake Formation, go to the Lake Formation dashboard, and remove the data lake locales and the Lake Formation administrator.

Conclusion 

Now that the solution is implemented, you have an automated anonymization dataflow. This solution demonstrates how you can build a solution using AWS serverless solutions where you only pay for what you use and without worrying about infrastructure provisioning. In addition, this solution is customizable to meet other data protection requirements such as General Data Protection Law (LGPD) in Brazil, General Data Protection Regulation in Europe (GDPR), and the Association of Banks in Singapore (ABS) Cloud Computing Implementation Guide.

We used Macie to identify the sensitive data stored in Amazon S3 and AWS Glue to generate Macie reports to anonymize the sensitive data found. Finally, we used Lake Formation to implement fine-grained data access control to specific information and demonstrated how you can programmatically grant access to applications that need to work with unmasked data.

Related links

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Iris Ferreira

Iris Ferreira

Iris is a solutions architect at AWS, supporting clients in their innovation and digital transformation journeys in the cloud. In her free time, she enjoys going to the beach, traveling, hiking and always being in contact with nature.

Paulo Aragão

Paulo Aragão

Paulo is a Principal Solutions Architect and supports clients in the financial sector to tread the new world of DeFi, web3.0, Blockchain, dApps, and Smart Contracts. In addition, he has extensive experience in high performance computing (HPC) and machine learning. Passionate about music and diving, he devours books, plays World of Warcraft and New World, and cooks for friends.

Leo da Silva

Leo da Silva

Leo is a Principal Security Solutions Architect at AWS and uses his knowledge to help customers better use cloud services and technologies securely. Over the years, he had the opportunity to work in large, complex environments, designing, architecting, and implementing highly scalable and secure solutions to global companies. He is passionate about football, BBQ, and Jiu Jitsu — the Brazilian version of them all.

Export a Software Bill of Materials using Amazon Inspector

Post Syndicated from Varun Sharma original https://aws.amazon.com/blogs/security/export-a-software-bill-of-materials-using-amazon-inspector/

Amazon Inspector is an automated vulnerability management service that continually scans Amazon Web Services (AWS) workloads for software vulnerabilities and unintended network exposure. Amazon Inspector has expanded capability that allows customers to export a consolidated Software Bill of Materials (SBOM) for supported Amazon Inspector monitored resources, excluding Windows EC2 instances.

Customers have asked us to provide additional software application inventory collected from Amazon Inspector monitored resources. This makes it possible to precisely track the software supply chain and security threats that might be connected to the results of the current Amazon Inspector. Generating an SBOM gives you critical security information that offers you visibility into specifics about your software supply chain, including the packages you use the most frequently and the related vulnerabilities that might affect your whole company.

This blog post includes steps that you can follow to export a consolidated SBOM for the resources monitored by Amazon Inspector across your organization in industry standard formats, including CycloneDx and SPDX. It also shares insights and approaches for analyzing SBOM artifacts using Amazon Athena.

Overview

An SBOM is defined as a nested inventory with a list of ingredients that make up software components. Security teams can export a consolidated SBOM to Amazon Simple Storage Service (Amazon S3) for an entire organization from the resource coverage page in the AWS Management Console for Amazon Inspector.

Using CycloneDx and SPDX industry standard formats, you can use insights gained from an SBOM to make decisions such as which software packages need to be updated across your organization or deprecated, if there’s no other option. Individual application or security engineers can also export an SBOM for a single resource or group of resources by applying filters for a specific account, resource type, resource ID, tags, or a combination of these as a part of the SBOM export workflow in the console or application programming interfaces.

Exporting SBOMs

To export Amazon Inspector SBOM reports to an S3 bucket, you must create and configure a bucket in the AWS Region where the SBOM reports are to be exported. You must configure your bucket permissions to allow only Amazon Inspector to put new objects into the bucket. This prevents other AWS services and users from adding objects to the bucket.

Each SBOM report is stored in an S3 bucket and has the name Cyclonedx_1_4 (Json) or Spdx_2_3-compatible (Json), depending on the export format that you specify. You can also use S3 event notifications to alert different operational teams that new SBOM reports have been exported.

Amazon Inspector requires that you use an AWS Key Management Service (AWS KMS) key to encrypt the SBOM report. The key must be a customer managed, symmetric KMS encryption key and must be in the same Region as the S3 bucket that you configured to store the SBOM report. The new KMS key for the SBOM report requires a key policy to be configured to grant permissions for Amazon Inspector to use the key. (Shown in Figure 1.)

Figure 1: Amazon Inspector SBOM export

Figure 1: Amazon Inspector SBOM export

Deploy prerequisites

The AWS CloudFormation template provided creates an S3 bucket with an associated bucket policy to enable Amazon Inspector to export SBOM report objects into the bucket. The template also creates a new KMS key to be used for SBOM report exports and grants the Amazon Inspector service permissions to use the key.

The export can be initiated from the AWS Inspector delegated administrator account or the AWS Inspector administrator account itself. This way, the S3 bucket contains reports for the AWS Inspector member accounts. To export the SBOM reports from Amazon Inspector deployed in the same Region, make sure the CloudFormation template is deployed within the AWS account and Region. If you enabled AWS Inspector in multiple accounts, the CloudFormation stack must be deployed in each Region where AWS Inspector is enabled.

To deploy the CloudFormation template

  1. Choose the following Launch Stack button to launch a CloudFormation stack in your account.

    Launch Stack

  2. Review the stack name and the parameters (MyKMSKeyName and MyS3BucketName) for the template. Note that the S3 bucket name must be unique.
  3. Choose Next and confirm the stack options.
  4. Go to the next page and choose Submit. The deployment of the CloudFormation stack will take 1–2 minutes.

After the CloudFormation stack has deployed successfully, you can use the S3 bucket and KMS key created by the stack to export SBOM reports.

Export SBOM reports

After setup is complete, you can export SBOM reports to an S3 bucket.

To export SBOM reports from the console

  1. Navigate to the AWS Inspector console in the same Region where the S3 bucket and KMS key were created.
  2. Select Export SBOMs from the navigation pane.
  3. Add filters to create reports for specific subsets of resources. The SBOMs for all active, supported resources are exported if you don’t supply a filter.
  4. Select the export file type you want. Options are Cyclonedx_1_4 (Json) or Spdx_2_3-compatible (Json).
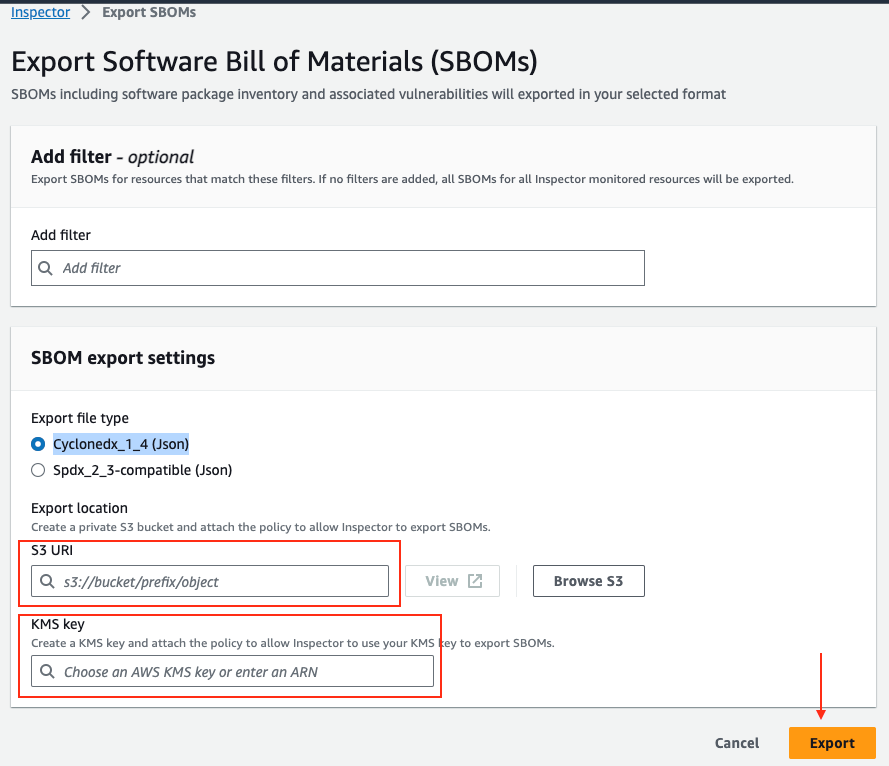
  5. Enter the S3 bucket URI from the output section of the CloudFormation template and enter the KMS key that was created.
  6. Choose Export. It can take 3–5 minutes to complete depending on the number of artifacts to be exported.
Figure 2: SBOM export configuration

Figure 2: SBOM export configuration

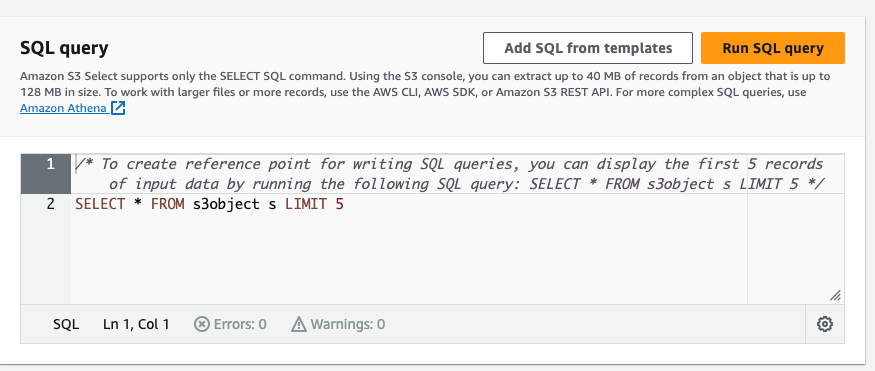
When complete, all SBOM artifacts will be in the S3 bucket. This gives you the flexibility to download the SBOM artifacts from the S3 bucket, or you can use Amazon S3 Select to retrieve a subset of data from an object using standard SQL queries.

Figure 3: Amazon S3 Select

Figure 3: Amazon S3 Select

You can also run advanced queries using Amazon Athena or create dashboards using Amazon QuickSight to gain insights and map trends.

Querying and visualization

With Athena, you can run SQL queries on raw data that’s stored in S3 buckets. The Amazon Inspector reports are exported to an S3 bucket, and you can query the data and create tables by following the Adding an AWS Glue crawler tutorial.

To enable AWS Glue to crawl the S3 data, you must add the role as described in the AWS Glue crawler tutorial to the AWS KMS key permissions so that AWS Glue can decrypt the S3 data.

The following is an example policy JSON that you can update for your use case. Make sure to replace the AWS account ID <111122223333> and S3 bucket name <DOC-EXAMPLE-BUCKET-111122223333> with your own information.

{
    "Sid": "Allow the AWS Glue crawler usage of the KMS key",
    "Effect": "Allow",
    "Principal": {
        "AWS": "arn:aws:iam::<111122223333>:role/service-role/AWSGlueServiceRole-S3InspectorSBOMReports"
    },
    "Action": [
        "kms:Decrypt",
        "kms:GenerateDataKey*"
    ],
    "Resource": "arn:aws:s3:::<DOC-EXAMPLE-BUCKET-111122223333>"
},

Note: The role created for AWS Glue also needs permission to read the S3 bucket where the reports are exported for creating the crawlers. The AWS Glue AWS Identity and Access Management (IAM) role allows the crawler to run and access your Amazon S3 data stores.

After an AWS Glue Data Catalog has been built, you can run the crawler on a scheduled basis to help ensure that it’s kept up to date with the latest Amazon Inspector SBOM manifests as they’re exported into the S3 bucket.

You can further navigate to the added table using the crawler and view the data in Athena. Using Athena, you can run queries against the Amazon Inspector reports to generate output data relevant to your environment. The schema for the generated SBOM report is different depending on the specific resources (Amazon Elastic Compute Cloud (Amazon EC2), AWS Lambda, Amazon Elastic Container Registry (Amazon ECR)) in the reports. So, depending on the schema, you can create a SQL Athena query to fetch information from the reports.

The following is an Athena example query that identifies the top 10 vulnerabilities for resources in an SBOM report. You can use the common vulnerability and exposures (CVE) IDs from the report to list the individual components affected by the CVEs.

SELECT
   account,
   vuln.id as vuln_id, 
   count(*) as vuln_count
FROM
   <Insert_table_name>,
   UNNEST(Inset_table_name.vulnerabilities)as t(vuln)
GROUP BY
   account,
   vuln.id
ORDER BY
vuln_count DESC
LIMIT 10;

The following Athena example query can be used to identify the top 10 operating systems (OS) along with the resource types and their count.

SELECT
   resource,
   metadata.component.name as os_name,
   count(*) as os_count 
FROM
   <Insert_table_name>
WHERE
   resource = 'AWS_LAMBDA_FUNCTION'
GROUP BY
   resource,
   metadata.component.name 
ORDER BY
   os_count DESC 
LIMIT 10;

If you have a package that has a critical vulnerability and you need to know if the package is used as a primary package or adds a dependency, you can use the following Athena sample query to check for the package in your application. In this example, I’m searching for a Log4j package. The result returns account ID, resource type, package_name, and package_count.

SELECT
   account,
   resource,
   comp.name as package_name,
   count(*) as package_count 
FROM
   <Insert_Table _name>,
   UNNEST(<Insert_Table_name>.components) as t(comp) 
WHERE
   comp.name = 'Log4j' 
GROUP BY
   account,
   comp.name,
   resource 
ORDER BY
   package_count DESC 
LIMIT 10 ;

Note: The sample Athena queries must be customized depending on the schema of the SBOM export report.

To further extend this solution, you can use Amazon QuickSight to produce dashboards to visualize the data by connecting to the AWS Glue table.

Conclusion

The new SBOM generation capabilities in Amazon Inspector improve visibility into the software supply chain by providing a comprehensive list of software packages across multiple levels of dependencies. You can also use SBOMs to monitor the licensing information for each of the software packages and identify potential licensing violations in your organization, helping you avoid potential legal risks.

The most important benefit of SBOM export is to help you comply with industry regulations and standards. By providing an industry-standard format (SPDX and CycloneDX) and enabling easy integration with other tools, systems, or services (such as Nexus IQ and WhiteSource), you can streamline the incident response processes, improve the accuracy and speed of security assessments, and adhere to compliance with regulatory requirements.

In addition to these benefits, the SBOM export feature provides a comprehensive and accurate understanding of the OS packages and software libraries found in their resources, further enhancing your ability to adhere to industry regulations and standards.

 
If you have feedback about this post, submit comments in the Comments section below. If you have any question/query in regard to information shared in this post, start a new thread on the AWS IAM Identity Center re:Post or contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Varun Sharma

Varun Sharma

Varun is an AWS Cloud Security Engineer who wears his security cape proudly. With a knack for unravelling the mysteries of Amazon Cognito and IAM, Varun is a go-to subject matter expert for these services. When he’s not busy securing the cloud, you’ll find him in the world of security penetration testing. And when the pixels are at rest, Varun switches gears to capture the beauty of nature through the lens of his camera.

Use Amazon Athena with Spark SQL for your open-source transactional table formats

Post Syndicated from Pathik Shah original https://aws.amazon.com/blogs/big-data/use-amazon-athena-with-spark-sql-for-your-open-source-transactional-table-formats/

AWS-powered data lakes, supported by the unmatched availability of Amazon Simple Storage Service (Amazon S3), can handle the scale, agility, and flexibility required to combine different data and analytics approaches. As data lakes have grown in size and matured in usage, a significant amount of effort can be spent keeping the data consistent with business events. To ensure files are updated in a transactionally consistent manner, a growing number of customers are using open-source transactional table formats such as Apache Iceberg, Apache Hudi, and Linux Foundation Delta Lake that help you store data with high compression rates, natively interface with your applications and frameworks, and simplify incremental data processing in data lakes built on Amazon S3. These formats enable ACID (atomicity, consistency, isolation, durability) transactions, upserts, and deletes, and advanced features such as time travel and snapshots that were previously only available in data warehouses. Each storage format implements this functionality in slightly different ways; for a comparison, refer to Choosing an open table format for your transactional data lake on AWS.

In 2023, AWS announced general availability for Apache Iceberg, Apache Hudi, and Linux Foundation Delta Lake in Amazon Athena for Apache Spark, which removes the need to install a separate connector or associated dependencies and manage versions, and simplifies the configuration steps required to use these frameworks.

In this post, we show you how to use Spark SQL in Amazon Athena notebooks and work with Iceberg, Hudi, and Delta Lake table formats. We demonstrate common operations such as creating databases and tables, inserting data into the tables, querying data, and looking at snapshots of the tables in Amazon S3 using Spark SQL in Athena.

Prerequisites

Complete the following prerequisites:

Download and import example notebooks from Amazon S3

To follow along, download the notebooks discussed in this post from the following locations:

After you download the notebooks, import them into your Athena Spark environment by following the To import a notebook section in Managing notebook files.

Navigate to specific Open Table Format section

If you are interested in Iceberg table format, navigate to Working with Apache Iceberg tables section.

If you are interested in Hudi table format, navigate to Working with Apache Hudi tables section.

If you are interested in Delta Lake table format, navigate to Working with Linux foundation Delta Lake tables section.

Working with Apache Iceberg tables

When using Spark notebooks in Athena, you can run SQL queries directly without having to use PySpark. We do this by using cell magics, which are special headers in a notebook cell that change the cell’s behavior. For SQL, we can add the %%sql magic, which will interpret the entire cell contents as a SQL statement to be run on Athena.

In this section, we show how you can use SQL on Apache Spark for Athena to create, analyze, and manage Apache Iceberg tables.

Set up a notebook session

In order to use Apache Iceberg in Athena, while creating or editing a session, select the Apache Iceberg option by expanding the Apache Spark properties section. It will pre-populate the properties as shown in the following screenshot.

This image shows the Apache Iceberg properties set while creating Spak session in Athena.

For steps, see Editing session details or Creating your own notebook.

The code used in this section is available in the SparkSQL_iceberg.ipynb file to follow along.

Create a database and Iceberg table

First, we create a database in the AWS Glue Data Catalog. With the following SQL, we can create a database called icebergdb:

%%sql
CREATE DATABASE icebergdb

Next, in the database icebergdb, we create an Iceberg table called noaa_iceberg pointing to a location in Amazon S3 where we will load the data. Run the following statement and replace the location s3://<your-S3-bucket>/<prefix>/ with your S3 bucket and prefix:

%%sql
CREATE TABLE icebergdb.noaa_iceberg(
station string,
date string,
latitude string,
longitude string,
elevation string,
name string,
temp string,
temp_attributes string,
dewp string,
dewp_attributes string,
slp string,
slp_attributes string,
stp string,
stp_attributes string,
visib string,
visib_attributes string,
wdsp string,
wdsp_attributes string,
mxspd string,
gust string,
max string,
max_attributes string,
min string,
min_attributes string,
prcp string,
prcp_attributes string,
sndp string,
frshtt string)
USING iceberg
PARTITIONED BY (year string)
LOCATION 's3://<your-S3-bucket>/<prefix>/noaaiceberg/'

Insert data into the table

To populate the noaa_iceberg Iceberg table, we insert data from the Parquet table sparkblogdb.noaa_pq that was created as part of the prerequisites. You can do this using an INSERT INTO statement in Spark:

%%sql
INSERT INTO icebergdb.noaa_iceberg select * from sparkblogdb.noaa_pq

Alternatively, you can use CREATE TABLE AS SELECT with the USING iceberg clause to create an Iceberg table and insert data from a source table in one step:

%%sql
CREATE TABLE icebergdb.noaa_iceberg
USING iceberg
PARTITIONED BY (year)
AS SELECT * FROM sparkblogdb.noaa_pq

Query the Iceberg table

Now that the data is inserted in the Iceberg table, we can start analyzing it. Let’s run a Spark SQL to find the minimum recorded temperature by year for the 'SEATTLE TACOMA AIRPORT, WA US' location:

%%sql
select name, year, min(MIN) as minimum_temperature
from icebergdb.noaa_iceberg
where name = 'SEATTLE TACOMA AIRPORT, WA US'
group by 1,2

We get following output.

Image shows output of first select query

Update data in the Iceberg table

Let’s look at how to update data in our table. We want to update the station name 'SEATTLE TACOMA AIRPORT, WA US' to 'Sea-Tac'. Using Spark SQL, we can run an UPDATE statement against the Iceberg table:

%%sql
UPDATE icebergdb.noaa_iceberg
SET name = 'Sea-Tac'
WHERE name = 'SEATTLE TACOMA AIRPORT, WA US'

We can then run the previous SELECT query to find the minimum recorded temperature for the 'Sea-Tac' location:

%%sql
select name, year, min(MIN) as minimum_temperature
from icebergdb.noaa_iceberg
where name = 'Sea-Tac'
group by 1,2

We get the following output.

Image shows output of second select query

Compact data files

Open table formats like Iceberg work by creating delta changes in file storage, and tracking the versions of rows through manifest files. More data files leads to more metadata stored in manifest files, and small data files often cause an unnecessary amount of metadata, resulting in less efficient queries and higher Amazon S3 access costs. Running Iceberg’s rewrite_data_files procedure in Spark for Athena will compact data files, combining many small delta change files into a smaller set of read-optimized Parquet files. Compacting files speeds up the read operation when queried. To run compaction on our table, run the following Spark SQL:

%%sql
CALL spark_catalog.system.rewrite_data_files
(table => 'icebergdb.noaa_iceberg', strategy=>'sort', sort_order => 'zorder(name)')

rewrite_data_files offers options to specify your sort strategy, which can help reorganize and compact data.

List table snapshots

Each write, update, delete, upsert, and compaction operation on an Iceberg table creates a new snapshot of a table while keeping the old data and metadata around for snapshot isolation and time travel. To list the snapshots of an Iceberg table, run the following Spark SQL statement:

%%sql
SELECT *
FROM spark_catalog.icebergdb.noaa_iceberg.snapshots

Expire old snapshots

Regularly expiring snapshots is recommended to delete data files that are no longer needed, and to keep the size of table metadata small. It will never remove files that are still required by a non-expired snapshot. In Spark for Athena, run the following SQL to expire snapshots for the table icebergdb.noaa_iceberg that are older than a specific timestamp:

%%sql
CALL spark_catalog.system.expire_snapshots
('icebergdb.noaa_iceberg', TIMESTAMP '2023-11-30 00:00:00.000')

Note that the timestamp value is specified as a string in format yyyy-MM-dd HH:mm:ss.fff. The output will give a count of the number of data and metadata files deleted.

Drop the table and database

You can run the following Spark SQL to clean up the Iceberg tables and associated data in Amazon S3 from this exercise:

%%sql
DROP TABLE icebergdb.noaa_iceberg PURGE

Run the following Spark SQL to remove the database icebergdb:

%%sql
DROP DATABASE icebergdb

To learn more about all the operations you can perform on Iceberg tables using Spark for Athena, refer to Spark Queries and Spark Procedures in the Iceberg documentation.

Working with Apache Hudi tables

Next, we show how you can use SQL on Spark for Athena to create, analyze, and manage Apache Hudi tables.

Set up a notebook session

In order to use Apache Hudi in Athena, while creating or editing a session, select the Apache Hudi option by expanding the Apache Spark properties section.

This image shows the Apache Hudi properties set while creating Spak session in Athena.

For steps, see Editing session details or Creating your own notebook.

The code used in this section should be available in the SparkSQL_hudi.ipynb file to follow along.

Create a database and Hudi table

First, we create a database called hudidb that will be stored in the AWS Glue Data Catalog followed by Hudi table creation:

%%sql
CREATE DATABASE hudidb

We create a Hudi table pointing to a location in Amazon S3 where we will load the data. Note that the table is of copy-on-write type. It is defined by type= 'cow' in the table DDL. We have defined station and date as the multiple primary keys and preCombinedField as year. Also, the table is partitioned on year. Run the following statement and replace the location s3://<your-S3-bucket>/<prefix>/ with your S3 bucket and prefix:

%%sql
CREATE TABLE hudidb.noaa_hudi(
station string,
date string,
latitude string,
longitude string,
elevation string,
name string,
temp string,
temp_attributes string,
dewp string,
dewp_attributes string,
slp string,
slp_attributes string,
stp string,
stp_attributes string,
visib string,
visib_attributes string,
wdsp string,
wdsp_attributes string,
mxspd string,
gust string,
max string,
max_attributes string,
min string,
min_attributes string,
prcp string,
prcp_attributes string,
sndp string,
frshtt string,
year string)
USING HUDI
PARTITIONED BY (year)
TBLPROPERTIES(
primaryKey = 'station, date',
preCombineField = 'year',
type = 'cow'
)
LOCATION 's3://<your-S3-bucket>/<prefix>/noaahudi/'

Insert data into the table

Like with Iceberg, we use the INSERT INTO statement to populate the table by reading data from the sparkblogdb.noaa_pq table created in the previous post:

%%sql
INSERT INTO hudidb.noaa_hudi select * from sparkblogdb.noaa_pq

Query the Hudi table

Now that the table is created, let’s run a query to find the maximum recorded temperature for the 'SEATTLE TACOMA AIRPORT, WA US' location:

%%sql
select name, year, max(MAX) as maximum_temperature
from hudidb.noaa_hudi
where name = 'SEATTLE TACOMA AIRPORT, WA US'
group by 1,2

Update data in the Hudi table

Let’s change the station name 'SEATTLE TACOMA AIRPORT, WA US' to 'Sea–Tac'. We can run an UPDATE statement on Spark for Athena to update the records of the noaa_hudi table:

%%sql
UPDATE hudidb.noaa_hudi
SET name = 'Sea-Tac'
WHERE name = 'SEATTLE TACOMA AIRPORT, WA US'

We run the previous SELECT query to find the maximum recorded temperature for the 'Sea-Tac' location:

%%sql
select name, year, max(MAX) as maximum_temperature
from hudidb.noaa_hudi
where name = 'Sea-Tac'
group by 1,2

Run time travel queries

We can use time travel queries in SQL on Athena to analyze past data snapshots. For example:

%%sql
select name, year, max(MAX) as maximum_temperature
from hudidb.noaa_hudi timestamp as of '2023-12-01 23:53:43.100'
where name = 'SEATTLE TACOMA AIRPORT, WA US'
group by 1,2

This query checks the Seattle Airport temperature data as of a specific time in the past. The timestamp clause lets us travel back without altering current data. Note that the timestamp value is specified as a string in format yyyy-MM-dd HH:mm:ss.fff.

Optimize query speed with clustering

To improve query performance, you can perform clustering on Hudi tables using SQL in Spark for Athena:

%%sql
CALL run_clustering(table => 'hudidb.noaa_hudi', order => 'name')

Compact tables

Compaction is a table service employed by Hudi specifically in Merge On Read (MOR) tables to merge updates from row-based log files to the corresponding columnar-based base file periodically to produce a new version of the base file. Compaction is not applicable to Copy On Write (COW) tables and only applies to MOR tables. You can run the following query in Spark for Athena to perform compaction on MOR tables:

%%sql
CALL run_compaction(op => 'run', table => 'hudi_table_mor');

Drop the table and database

Run the following Spark SQL to remove the Hudi table you created and associated data from the Amazon S3 location:

%%sql
DROP TABLE hudidb.noaa_hudi PURGE

Run the following Spark SQL to remove the database hudidb:

%%sql
DROP DATABASE hudidb

To learn about all the operations you can perform on Hudi tables using Spark for Athena, refer to SQL DDL and Procedures in the Hudi documentation.

Working with Linux foundation Delta Lake tables

Next, we show how you can use SQL on Spark for Athena to create, analyze, and manage Delta Lake tables.

Set up a notebook session

In order to use Delta Lake in Spark for Athena, while creating or editing a session, select Linux Foundation Delta Lake by expanding the Apache Spark properties section.

This image shows the Delta Lake properties set while creating Spak session in Athena.

For steps, see Editing session details or Creating your own notebook.

The code used in this section should be available in the SparkSQL_delta.ipynb file to follow along.

Create a database and Delta Lake table

In this section, we create a database in the AWS Glue Data Catalog. Using following SQL, we can create a database called deltalakedb:

%%sql
CREATE DATABASE deltalakedb

Next, in the database deltalakedb, we create a Delta Lake table called noaa_delta pointing to a location in Amazon S3 where we will load the data. Run the following statement and replace the location s3://<your-S3-bucket>/<prefix>/ with your S3 bucket and prefix:

%%sql
CREATE TABLE deltalakedb.noaa_delta(
station string,
date string,
latitude string,
longitude string,
elevation string,
name string,
temp string,
temp_attributes string,
dewp string,
dewp_attributes string,
slp string,
slp_attributes string,
stp string,
stp_attributes string,
visib string,
visib_attributes string,
wdsp string,
wdsp_attributes string,
mxspd string,
gust string,
max string,
max_attributes string,
min string,
min_attributes string,
prcp string,
prcp_attributes string,
sndp string,
frshtt string)
USING delta
PARTITIONED BY (year string)
LOCATION 's3://<your-S3-bucket>/<prefix>/noaadelta/'

Insert data into the table

We use an INSERT INTO statement to populate the table by reading data from the sparkblogdb.noaa_pq table created in the previous post:

%%sql
INSERT INTO deltalakedb.noaa_delta select * from sparkblogdb.noaa_pq

You can also use CREATE TABLE AS SELECT to create a Delta Lake table and insert data from a source table in one query.

Query the Delta Lake table

Now that the data is inserted in the Delta Lake table, we can start analyzing it. Let’s run a Spark SQL to find the minimum recorded temperature for the 'SEATTLE TACOMA AIRPORT, WA US' location:

%%sql
select name, year, max(MAX) as minimum_temperature
from deltalakedb.noaa_delta
where name = 'SEATTLE TACOMA AIRPORT, WA US'
group by 1,2

Update data in the Delta lake table

Let’s change the station name 'SEATTLE TACOMA AIRPORT, WA US' to 'Sea–Tac'. We can run an UPDATE statement on Spark for Athena to update the records of the noaa_delta table:

%%sql
UPDATE deltalakedb.noaa_delta
SET name = 'Sea-Tac'
WHERE name = 'SEATTLE TACOMA AIRPORT, WA US'

We can run the previous SELECT query to find the minimum recorded temperature for the 'Sea-Tac' location, and the result should be the same as earlier:

%%sql
select name, year, max(MAX) as minimum_temperature
from deltalakedb.noaa_delta
where name = 'Sea-Tac'
group by 1,2

Compact data files

In Spark for Athena, you can run OPTIMIZE on the Delta Lake table, which will compact the small files into larger files, so the queries are not burdened by the small file overhead. To perform the compaction operation, run the following query:

%%sql
OPTIMIZE deltalakedb.noaa_delta

Refer to Optimizations in the Delta Lake documentation for different options available while running OPTIMIZE.

Remove files no longer referenced by a Delta Lake table

You can remove files stored in Amazon S3 that are no longer referenced by a Delta Lake table and are older than the retention threshold by running the VACCUM command on the table using Spark for Athena:

%%sql
VACUUM deltalakedb.noaa_delta

Refer to Remove files no longer referenced by a Delta table in the Delta Lake documentation for options available with VACUUM.

Drop the table and database

Run the following Spark SQL to remove the Delta Lake table you created:

%%sql
DROP TABLE deltalakedb.noaa_delta

Run the following Spark SQL to remove the database deltalakedb:

%%sql
DROP DATABASE deltalakedb

Running DROP TABLE DDL on the Delta Lake table and database deletes the metadata for these objects, but doesn’t automatically delete the data files in Amazon S3. You can run the following Python code in the notebook’s cell to delete the data from the S3 location:

import boto3

s3 = boto3.resource('s3')
bucket = s3.Bucket('<your-S3-bucket>')
bucket.objects.filter(Prefix="<prefix>/noaadelta/").delete()

To learn more about the SQL statements that you can run on a Delta Lake table using Spark for Athena, refer to the quickstart in the Delta Lake documentation.

Conclusion

This post demonstrated how to use Spark SQL in Athena notebooks to create databases and tables, insert and query data, and perform common operations like updates, compactions, and time travel on Hudi, Delta Lake, and Iceberg tables. Open table formats add ACID transactions, upserts, and deletes to data lakes, overcoming limitations of raw object storage. By removing the need to install separate connectors, Spark on Athena’s built-in integration reduces configuration steps and management overhead when using these popular frameworks for building reliable data lakes on Amazon S3. To learn more about selecting an open table format for your data lake workloads, refer to Choosing an open table format for your transactional data lake on AWS.


About the Authors

Pathik Shah is a Sr. Analytics Architect on Amazon Athena. He joined AWS in 2015 and has been focusing in the big data analytics space since then, helping customers build scalable and robust solutions using AWS analytics services.

Raj Devnath is a Product Manager at AWS on Amazon Athena. He is passionate about building products customers love and helping customers extract value from their data. His background is in delivering solutions for multiple end markets, such as finance, retail, smart buildings, home automation, and data communication systems.

How to build a unified authorization layer for identity providers with Amazon Verified Permissions

Post Syndicated from Akash Kumar original https://aws.amazon.com/blogs/security/how-to-build-a-unified-authorization-layer-for-identity-providers-with-amazon-verified-permissions/

Enterprises often have an identity provider (IdP) for their employees and another for their customers. Using multiple IdPs allows you to apply different access controls and policies for employees and for customers. However, managing multiple identity systems can be complex. A unified authorization layer can ease administration by centralizing access policies for APIs regardless of the user’s IdP. The authorization layer evaluates access tokens from any authorized IdP before allowing API access. This removes authorization logic from the APIs and simplifies specifying organization-wide policies. Potential drawbacks include additional complexity in the authorization layer. However, simplifying the management of policies reduces cost of ownership and the likelihood of errors.

Consider a veterinary clinic that has an IdP for their employees. Their clients, the pet owners, would have a separate IdP. Employees might have different sign-in requirements than the clients. These requirements could include features such as multi-factor authentication (MFA) or additional auditing functionality. Applying identical access controls for clients may not be desirable. The clinic’s scheduling application would manage access from both the clinic employees and pet owners. By implementing a unified authorization layer, the scheduling app doesn’t need to be aware of the different IdPs or tokens. The authorization layer handles evaluating tokens and applying policies, such as allowing the clinic employees full access to appointment data while limiting pet owners to just their pet’s records. In this post, we show you an architecture for this situation that demonstrates how to build a unified authorization layer using multiple Amazon Cognito user pools, Amazon Verified Permissions, and an AWS Lambda authorizer for Amazon API Gateway-backed APIs.

In the architecture, API Gateway exposes APIs to provide access to backend resources. API Gateway is a fully-managed service that allows developers to build APIs that act as an entry point for applications. To integrate API Gateway with multiple IdPs, you can use a Lambda authorizer to control access to the API. The IdP in this architecture is Amazon Cognito, which provides the authentication function for users before they’re authorized by Verified Permissions, which implements fine-grained authorization on resources in an application. Keep in mind that Verified Permissions has limits on policy sizes and requests per second. Large deployments might require a different policy store or a caching layer. The four services work together to combine multiple IdPs into a unified authorization layer. The architecture isn’t limited to the Cognito IdP — third-party IdPs that generate JSON Web Tokens (JWTs) can be used, including combinations of different IdPs.

Architecture overview

This sample architecture relies on user-pool multi-tenancy for user authentication. It uses Cognito user pools to assign authenticated users a set of temporary and least-privilege credentials for application access. Once users are authenticated, they are authorized to access backend functions via a Lambda Authorizer function. This function interfaces with Verified Permissions to apply the appropriate access policy based on user attributes.

This sample architecture is based on the scenario of an application that has two sets of users: an internal set of users, veterinarians, as well as an external set of users, clients, with each group having specific access to the API. Figure 1 shows the user request flow.

Figure 1: User request flow

Figure 1: User request flow

Let’s go through the request flow to understand what happens at each step, as shown in Figure 1:

  1. There two groups of users — External (Clients) and Internal (Veterinarians). These user groups sign in through a web portal that authenticates against an IdP (Amazon Cognito).
  2. The groups attempt to access the get appointment API through API Gateway, along with their JWT tokens with claims and client ID.
  3. The Lambda authorizer validates the claims.

    Note: If Cognito is the IdP, then Verified Permissions can authorize the user from their JWT directly with the IsAuthorizedWithToken API.

  4. After validating the JWT token, the Lambda authorizer makes a query to Verified Permissions with associated policy information to check the request.
  5. API Gateway evaluates the policy that the Lambda authorizer returned, to allow or deny access to the resource.
  6. If allowed, API Gateway accesses the resource. If denied, API Gateway returns a 403 Forbidden error.

Note: To further optimize the Lambda authorizer, the authorization decision can be cached or disabled, depending on your needs. By enabling caching, you can improve the performance, because the authorization policy will be returned from the cache whenever there is a cache key match. To learn more, see Configure a Lambda authorizer using the API Gateway console.

Walkthrough

This walkthrough demonstrates the preceding scenario for an authorization layer supporting veterinarians and clients. Each set of users will have their own distinct Amazon Cognito user pool.

Verified Permissions policies associated with each Cognito pool enforce access controls. In the veterinarian pool, veterinarians are only allowed to access data for their own patients. Similarly, in the client pool, clients are only able to view and access their own data. This keeps data properly segmented and secured between veterinarians and clients.

Internal policy

permit (principal in UserGroup::"AllVeterinarians",
   action == Action::"GET/appointment",
   resource in UserGroup::"AllVeterinarians")
   when {principal == resource.Veterinarian };

External policy

permit (principal in UserGroup::"AllClients",
   action == Action::"GET/appointment",
   resource in UserGroup::"AllClients")
   when {principal == resource.owner};

The example internal and external policies, along with Cognito serving as an IdP, allow the veterinarian users to federate in to the application through one IdP, while the external clients must use another IdP. This, coupled with the associated authorization policies, allows you to create and customize fine-grained access policies for each user group.

To validate the access request with the policy store, the Lambda authorizer execution role also requires the verifiedpermissions:IsAuthorized action.

Although our example Verified Permissions policies are relatively simple, Cedar policy language is extensive and allows you to define custom rules for your business needs. For example, you could develop a policy that allows veterinarians to access client records only during the day of the client’s appointment.

Implement the sample architecture

The architecture is based on a user-pool multi-tenancy for user authentication. It uses Amazon Cognito user pools to assign authenticated users a set of temporary and least privilege credentials for application access. After users are authenticated, they are authorized to access APIs through a Lambda function. This function interfaces with Verified Permissions to apply the appropriate access policy based on user attributes.

Prerequisites

You need the following prerequisites:

  • The AWS Command Line Interface (CLI) installed and configured for use.
  • Python 3.9 or later, to package Python code for Lambda.

    Note: We recommend that you use a virtual environment or virtualenvwrapper to isolate the sample from the rest of your Python environment.

  • An AWS Identity and Access Management (IAM) role or user with enough permissions to create an Amazon Cognito user pool, IAM role, Lambda function, IAM policy, and API Gateway instance.
  • jq for JSON processing in bash script.

    To install on Ubuntu/Debian, use the following command:

    sudo apt-get install jq

    To install on Mac with Homebrew, using the following command:

    brew install jq

  • The GitHub repository for the sample. You can download it, or you can use the following Git command to download it from your terminal.

    Note: This sample code should be used to test the solution and is not intended to be used in a production account.

    $ git clone https://github.com/aws-samples/amazon-cognito-avp-apigateway.git
    $ cd amazon-cognito-avp-apigateway

To implement this reference architecture, you will use the following services:

  • Amazon Verified Permissions is a service that helps you implement and enforce fine-grained authorization on resources within the applications that you build and deploy, such as HR systems and banking applications.
  • Amazon API Gateway is a fully managed service that developers can use to create, publish, maintain, monitor, and secure APIs at any scale.
  • AWS Lambda is a serverless compute service that lets you run code without provisioning or managing servers, creating workload-aware cluster scaling logic, maintaining event integrations, or managing runtimes.
  • Amazon Cognito provides an identity store that scales to millions of users, supports social and enterprise identity federation, and offers advanced security features to protect your consumers and business.

Note: We tested this architecture in the us-east-1 AWS Region. Before you select a Region, verify that the necessary services — Amazon Verified Permissions, Amazon Cognito, API Gateway, and Lambda — are available in those Regions.

Deploy the sample architecture

From within the directory where you downloaded the sample code from GitHub, first run the following command to package the Lambda functions. Then run the next command to generate a random Cognito user password and create the resources described in the previous section.

Note: In this case, you’re generating a random user password for demonstration purposes. Follow best practices for user passwords in production implementations.

$ bash ./helper.sh package-lambda-functions
 …
Successfully completed packaging files.
$ bash ./helper.sh cf-create-stack-gen-password
 …
Successfully created CloudFormation stack.

Validate Cognito user creation

Run the following commands to open the Cognito UI in your browser and then sign in with your credentials. This validates that the previous commands created Cognito users successfully.

Note: When you run the commands, they return the username and password that you should use to sign in.

For internal user pool domain users

$ bash ./helper.sh open-cognito-internal-domain-ui
 Opening Cognito UI...
 URL: xxxxxxxxx
 Please use following credentials to login:
 Username: cognitouser
 Password: xxxxxxxx

For external user pool domain users

$ bash ./helper.sh open-cognito-external-domain-ui
 Opening Cognito UI...
 URL: xxxxxxxxx
 Please use following credentials to login:
 Username: cognitouser
 Password: xxxxxxxx

Validate Cognito JWT upon sign in

Because you haven’t installed a web application that would respond to the redirect request, Cognito will redirect to localhost, which might look like an error. The key aspect is that after a successful sign-in, there is a URL similar to the following in the navigation bar of your browser.

http://localhost/#id_token=eyJraWQiOiJicVhMYWFlaTl4aUhzTnY3W...

Test the API configuration

Before you protect the API with Cognito so that only authorized users can access it, let’s verify that the configuration is correct and API Gateway serves the API. The following command makes a curl request to API Gateway to retrieve data from the API service.

$ bash ./helper.sh curl-api

API to check the appointment details of PI-T123
URL: https://epgst74zff.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T123
Response: 
{"appointment": {"id": "PI-T123", "name": "Dave", "Pet": "Onyx - Dog. 2y 3m", "Phone Number": "+1234567", "Visit History": "Patient History from last visit with primary vet", "Assigned Veterinarian": "Jane"}}

API to check the appointment details of PI-T124
URL: https://epgst74zff.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T124
Response: 
{"appointment": {"id": "PI-T124", "name": "Joy", "Pet": "Jelly - Dog. 6y 2m", "Phone Number": "+1368728", "Visit History": "None", "Assigned Veterinarian": "Jane"}}

API to check the appointment details of PI-T125
URL: https://epgst74zff.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T125
Response: 
{"appointment": {"id": "PI-T125", "name": "Dave", "Pet": "Sassy - Cat. 1y", "Phone Number": "+1398777", "Visit History": "Patient History from last visit with primary vet", "Assigned Veterinarian": "Adam"}}

Protect the API

In the next step, you deploy a Verified Permissions policy store and a Lambda authorizer. The policy store contains the policies for user authorization. The Lambda authorizer verifies users’ access tokens and authorizes the users through Verified Permissions.

Update and create resources

Run the following command to update existing resources and create a Lambda authorizer and Verified Permissions policy store.

$ bash ./helper.sh cf-update-stack
 Successfully updated CloudFormation stack.

Test the custom authorizer setup

Begin your testing with the following request, which doesn’t include an access token.

Note: Wait for a few minutes to allow API Gateway to deploy before you run the following commands.

$ bash ./helper.sh curl-api
API to check the appointment details of PI-T123
URL: https://epgst74zff.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T123
Response: 
{"message":"Unauthorized"}

API to check the appointment details of PI-T124
URL: https://epgst74zff.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T124
Response: 
{"message":"Unauthorized"}

API to check the appointment details of PI-T125
URL: https://epgst74zff.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T125
Response: 
{"message":"Unauthorized"}

The architecture denied the request with the message “Unauthorized.” At this point, API Gateway expects a header named Authorization (case sensitive) in the request. If there’s no authorization header, API Gateway denies the request before it reaches the Lambda authorizer. This is a way to filter out requests that don’t include required information.

Use the following command for the next test. In this test, you pass the required header, but the token is invalid because it wasn’t issued by Cognito and is instead a simple JWT-format token stored in ./helper.sh. To learn more about how to decode and validate a JWT, see Decode and verify a Cognito JSON token.

$ bash ./helper.sh curl-api-invalid-token
 {"Message":"User is not authorized to access this resource"}

This time the message is different. The Lambda authorizer received the request and identified the token as invalid and responded with the message “User is not authorized to access this resource.”

To make a successful request to the protected API, your code must perform the following steps:

  1. Use a user name and password to authenticate against your Cognito user pool.
  2. Acquire the tokens (ID token, access token, and refresh token).
  3. Make an HTTPS (TLS) request to API Gateway and pass the access token in the headers.

To finish testing, programmatically sign in to the Cognito UI, acquire a valid access token, and make a request to API Gateway. Run the following commands to call the protected internal and external APIs.

$ ./helper.sh curl-protected-internal-user-api

Getting API URL, Cognito Usernames, Cognito Users Password and Cognito ClientId...
User: Jane
Password: Pa%%word-2023-04-17-17-11-32
Resource: PI-T123
URL: https://16qyz501mg.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T123

Authenticating to get access_token...
Access Token: eyJraWQiOiJIaVRvckxxxxxxxxxx6BfCBKASA

Response: 
{"appointment": {"id": "PI-T123", "name": "Dave", "Pet": "Onyx - Dog. 2y 3m", "Phone Number": "+1234567", "Visit History": "Patient History from last visit with primary vet", "Assigned Veterinarian": "Jane"}}

User: Adam
Password: Pa%%word-2023-04-17-17-11-32
Resource: PI-T123
URL: https://16qyz501mg.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T123

Authenticating to get access_token...
Access Token: eyJraWQiOiJIaVRvckxxxxxxxxxx6BfCBKASA

Response: 
{"Message":"User is not authorized to access this resource"}

User: Adam
Password: Pa%%word-2023-04-17-17-11-32
Resource: PI-T125
URL: https://16qyz501mg.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T125

Authenticating to get access_token...
Access Token: eyJraWQiOiJIaVRvckxxxxxxxxxx6BfCBKASA

Response: 
{"appointment": {"id": "PI-T125", "name": "Dave", "Pet": "Sassy - Cat. 1y", "Phone Number": "+1398777", "Visit History": "Patient History from last visit with primary vet", "Assigned Veterinarian": "Adam"}}

Now calling external userpool users for accessing request

$ ./helper.sh curl-protected-external-user-api
User: Dave
Password: Pa%%word-2023-04-17-17-11-32
Resource: PI-T123
URL: https://16qyz501mg.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T123

Authenticating to get access_token...
Access Token: eyJraWQiOiJIaVRvckxxxxxxxxxx6BfCBKASA

Response: 
{"appointment": {"id": "PI-T123", "name": "Dave", "Pet": "Onyx - Dog. 2y 3m", "Phone Number": "+1234567", "Visit History": "Patient History from last visit with primary vet", "Assigned Veterinarian": "Jane"}}

User: Joy
Password Pa%%word-2023-04-17-17-11-32
Resource: PI-T123
URL: https://16qyz501mg.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T123

Authenticating to get access_token...
Access Token: eyJraWQiOiJIaVRvckxxxxxxxxxx6BfCBKASA

Response: 
{"Message":"User is not authorized to access this resource"}

User: Joy
Password Pa%%word-2023-04-17-17-11-32
Resource: PI-T124
URL: https://16qyz501mg.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T124

Authenticating to get access_token...
Access Token: eyJraWQiOiJIaVRvckxxxxxxxxxx6BfCBKASA

Response: 
{"appointment": {"id": "PI-T124", "name": "Joy", "Pet": "Jelly - Dog. 6y 2m", "Phone Number": "+1368728", "Visit History": "None", "Assigned Veterinarian": "Jane"}}

This time, you receive a response with data from the API service. Let’s recap the steps that the example code performed:

  1. The Lambda authorizer validates the access token.
  2. The Lambda authorizer uses Verified Permissions to evaluate the user’s requested actions against the policy store.
  3. The Lambda authorizer passes the IAM policy back to API Gateway.
  4. API Gateway evaluates the IAM policy, and the final effect is an allow.
  5. API Gateway forwards the request to Lambda.
  6. Lambda returns the response.

In each of the tests, internal and external, the architecture denied the request because the Verified Permissions policies denied access to the user. In the internal user pool, the policies only allow veterinarians to see their own patients’ data. Similarly, in the external user pool, the policies only allow clients to see their own data.

Clean up resources

Run the following command to delete the deployed resources and clean up.

$ bash ./helper.sh cf-delete-stack

Additional information

Verified Permissions is integrated with AWS CloudTrail, a service that provides a record of actions taken by a user, role, or AWS service in Verified Permissions. CloudTrail captures API calls for Verified Permissions as events. You can choose to capture actions performed on a Verified Permissions policy store by the Lambda authorizer. Verified Permissions logs can also be injected into your security information and event management (SEIM) solution for security analysis and compliance. For information about API call quotas, see Quotas for Amazon Verified Permission.

Conclusion

In this post, we demonstrated how you can use multiple Amazon Cognito user pools alongside Amazon Verified Permissions to build a single access layer to APIs. We used Cognito in this example, but you could implement the solution with another third-party IdP instead. As a next step, explore the Cedar playground to test policies that can be used with Verified Permissions, or expand this solution by integrating a third-party IdP.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Author

Akash Kumar

Akash is a Senior Lead Consultant at AWS, based in India. He works with customers for application development, security, and DevOps to modernize and re-architect their workloads to the AWS Cloud. His passion is building innovative solutions and automating infrastructure, enabling customers to focus more on their businesses.

Brett Seib

Brett Seib

Brett is a Senior Solutions Architect, based in Austin, Texas. He is passionate about innovating and using technology to solve business challenges for customers. Brett has several years of experience in the enterprise, Internet of Things (IoT), and data analytics industries, accelerating customer business outcomes.

John Thach

John Thach

John is a Technical Account Manager, based in Houston, Texas. He focuses on enabling customers to implement resilient, secure, and cost-effective solutions by using AWS services. He is passionate about helping customers solve unique challenges through their cloud journeys.

How to use AWS Database Encryption SDK for client-side encryption and perform searches on encrypted attributes in DynamoDB tables

Post Syndicated from Samit Kumbhani original https://aws.amazon.com/blogs/security/how-to-use-aws-database-encryption-sdk-for-client-side-encryption-and-perform-searches-on-encrypted-attributes-in-dynamodb-tables/

Today’s applications collect a lot of data from customers. The data often includes personally identifiable information (PII), that must be protected in compliance with data privacy laws such as the General Data Protection Regulation (GDPR) and the California Consumer Privacy Act (CCPA). Modern business applications require fast and reliable access to customer data, and Amazon DynamoDB is an ideal choice for high-performance applications at scale. While server-side encryption options exist to safeguard customer data, developers can also add client-side encryption to further enhance the security of their customer’s data.

In this blog post, we show you how the AWS Database Encryption SDK (DB-ESDK) – an upgrade to the DynamoDB Encryption Client – provides client-side encryption to protect sensitive data in transit and at rest. At its core, the DB-ESDK is a record encryptor that encrypts, signs, verifies, and decrypts the records in DynamoDB table. You can also use DB-ESDK to search on encrypted records and retrieve data, thereby alleviating the need to download and decrypt your entire dataset locally. In this blog, we demonstrate how to use DB-ESDK to build application code to perform client-side encryption of sensitive data within your application before transmitting and storing it in DynamoDB and then retrieve data by searching on encrypted fields.

Client-side encryption

For protecting data at rest, many AWS services integrate with AWS Key Management Service (AWS KMS). When you use server-side encryption, your plaintext data is encrypted in transit over an HTTPS connection, decrypted at the service endpoint, and then re-encrypted by the service before being stored. Client-side encryption is the act of encrypting your data locally to help ensure its security in transit and at rest. When using client-side encryption, you encrypt the plaintext data from the source (for example, your application) before you transmit the data to an AWS service. This verifies that only the authorized users with the right permission to the encryption key can decrypt the ciphertext data. Because data is encrypted inside an environment that you control, it is not exposed to a third party, including AWS.

While client-side encryption can be used to improve overall security posture, it introduces additional complexity on the application, including managing keys and securely executing cryptographic tasks. Furthermore, client-side encryption often results in reduced portability of the data. After data is encrypted and written to the database, it’s generally not possible to perform additional tasks such as creating index on the data or search directly on the encrypted records without first decrypting it locally. In the next section, you’ll see how you can address these issues by using the AWS Database Encryption SDK (DB-ESDK)—to implement client-side encryption in your DynamoDB workloads and perform searches.

AWS Database Encryption SDK

DB-ESDK can be used to encrypt sensitive attributes such as those containing PII attributes before storing them in your DynamoDB table. This enables your application to help protect sensitive data in transit and at rest, because data cannot be exposed unless decrypted by your application. You can also use DB-ESDK to find information by searching on encrypted attributes while your data remains securely encrypted within the database.

In regards to key management, DB-ESDK gives you direct control over the data by letting you supply your own encryption key. If you’re using AWS KMS, you can use key policies to enforce clear separation between the authorized users who can access specific encrypted data and those who cannot. If your application requires storing multiple tenant’s data in single table, DB-ESDK supports configuring distinct key for each of those tenants to ensure data protection. Follow this link to view how searchable encryption works for multiple tenant databases.

While DB-ESDK provides many features to help you encrypt data in your database, in this blog post, we focus on demonstrating the ability to search on encrypted data.

How the AWS Database Encryption SDK works with DynamoDB

Figure 1: DB-ESDK overview

Figure 1: DB-ESDK overview

As illustrated in Figure 1, there are several steps that you must complete before you can start using the AWS Database Encryption SDK. First, you need to set up your cryptographic material provider library (MPL), which provides you with the lower level abstraction layer for managing cryptographic materials (that is, keyrings and wrapping keys) used for encryption and decryption. The MPL provides integration with AWS KMS as your keyring and allows you to use a symmetric KMS key as your wrapping key. When data needs to be encrypted, DB-ESDK uses envelope encryption and asks the keyring for encryption material. The material consists of a plaintext data key and an encrypted data key, which is encrypted with the wrapping key. DB-ESDK uses the plaintext data key to encrypt the data and stores the ciphertext data key with the encrypted data. This process is reversed for decryption.

The AWS KMS hierarchical keyring goes one step further by introducing a branch key between the wrapping keys and data keys. Because the branch key is cached, it reduces the number of network calls to AWS KMS, providing performance and cost benefits. The hierarchical keyring uses a separate DynamoDB table is referred as the keystore table that must be created in advance. The mapping of wrapping keys to branch keys to data keys is handled automatically by the MPL.

Next, you need to set up the main DynamoDB table for your application. The Java version of DB-ESDK for DynamoDB provides attribute level actions to let you define which attribute should be encrypted. To allow your application to search on encrypted attribute values, you also must configure beacons, which are truncated hashes of plaintext value that create a map between the plaintext and encrypted value and are used to perform the search. These configuration steps are done once for each DynamoDB table. When using beacons, there are tradeoffs between how efficient your queries are and how much information is indirectly revealed about the distribution of your data. You should understand the tradeoff between security and performance before deciding if beacons are right for your use case.

After the MPL and DynamoDB table are set up, you’re ready to use DB-ESDK to perform client-side encryption. To better understand the preceding steps, let’s dive deeper into an example of how this all comes together to insert data and perform searches on a DynamoDB table.

AWS Database Encryption SDK in action

Let’s review the process of setting up DB-ESDK and see it in action. For the purposes of this blog post, let’s build a simple application to add records and performs searches.

The following is a sample plaintext record that’s received by the application:

{
"order_id": "ABC-10001",
“order_time”: “1672531500”,
“email”: "[email protected]",
"first_name": "John",
"last_name": "Doe",
"last4_creditcard": "4567"
"expiry_date": 082026
}

Prerequisite: For client side encryption to work, set up the integrated development environment (IDE) of your choice or set up AWS Cloud9.

Note: To focus on DB-ESDK capabilities, the following instructions omit basic configuration details for DynamoDB and AWS KMS.

Configure DB-ESDK cryptography

As mentioned previously, you must set up the MPL. For this example, you use an AWS KMS hierarchical keyring.

  1. Create KMS key: Create the wrapping key for your keyring. To do this, create a symmetric KMS key using the AWS Management Console or the API.
  2. Create keystore table: Create a DynamoDB table to serve as a keystore to hold the branch keys. The logical keystore name is cryptographically bound to the data stored in the keystore table. The logical keystore name can be the same as your DynamoDB table name, but it doesn’t have to be.
    private static void keyStoreCreateTable(String keyStoreTableName,
                                           String logicalKeyStoreName,
                                           String kmsKeyArn) {
        
        final KeyStore keystore = KeyStore.builder().KeyStoreConfig(
                KeyStoreConfig.builder()
                        .ddbClient(DynamoDbClient.create())
                        .ddbTableName(keyStoreTableName)
                        .logicalKeyStoreName(logicalKeyStoreName)
                        .kmsClient(KmsClient.create())
                        .kmsConfiguration(KMSConfiguration.builder()
                                .kmsKeyArn(kmsKeyArn)
                                .build())
                        .build()).build();
    
        
          keystore.CreateKeyStore(CreateKeyStoreInput.builder().build());
        // It may take a couple minutes for the table to reflect ACTIVE state
    }

  3. Create keystore keys: This operation generates the active branch key and beacon key using the KMS key from step 1 and stores it in the keystore table. The branch and beacon keys will be used by DB-ESDK for encrypting attributes and generating beacons.
    private static String keyStoreCreateKey(String keyStoreTableName,
                                             String logicalKeyStoreName,
                                             String kmsKeyArn) {
       
          final KeyStore keystore = KeyStore.builder().KeyStoreConfig(
                  KeyStoreConfig.builder()
                          .ddbClient(DynamoDbClient.create())
                          .ddbTableName(keyStoreTableName)
                          .logicalKeyStoreName(logicalKeyStoreName)
                          .kmsClient(KmsClient.create())
                          .kmsConfiguration(KMSConfiguration.builder()
                              .kmsKeyArn(kmsKeyArn)
                              .build())
                          .build()).build();
        
          final String branchKeyId = keystore.CreateKey(CreateKeyInput.builder().build()).branchKeyIdentifier();
          return branchKeyId;
      }

At this point, the one-time set up to configure the cryptography material is complete.

Set up a DynamoDB table and beacons

The second step is to set up your DynamoDB table for client-side encryption. In this step, define the attributes that you want to encrypt, define beacons to enable search on encrypted data, and set up the index to query the data. For this example, use the Java client-side encryption library for DynamoDB.

  1. Define DynamoDB table: Define the table schema and the attributes to be encrypted. For this blog post, lets define the schema based on the sample record that was shared previously. To do that, create a DynamoDB table called OrderInfo with order_id as the partition key and order_time as the sort key.

    DB-ESDK provides the following options to define the sensitivity level for each field. Define sensitivity level for each of the attributes based on your use case.

    • ENCRYPT_AND_SIGN: Encrypts and signs the attributes in each record using a unique encryption key. Choose this option for attributes with data you want to encrypt.
    • SIGN_ONLY: Adds a digital signature to verify the authenticity of your data. Choose this option for attributes that you would like to protect from being altered. The partition and sort key should always be set as SIGN_ONLY.
    • DO_NOTHING: Does not encrypt or sign the contents of the field and stores the data as-is. Only choose this option if the field doesn’t contain sensitive data and doesn’t need to be authenticated with the rest of your data. In this example, the partition key and sort key will be defined as “Sign_Only” attributes. All additional table attributes will be defined as “Encrypt and Sign”: email, firstname, lastname, last4creditcard and expirydate.
      private static DynamoDbClient configDDBTable(String ddbTableName, 
                                            IKeyring kmsKeyring, 
                                            List<BeaconVersion> beaconVersions){
      
          // Partition and Sort keys must be SIGN_ONLY
           
          final Map<String, CryptoAction> attributeActionsOnEncrypt = new HashMap<>();
          attributeActionsOnEncrypt.put("order_id", CryptoAction.SIGN_ONLY);
          attributeActionsOnEncrypt.put("order_time", CryptoAction.SIGN_ONLY);
          attributeActionsOnEncrypt.put("email", CryptoAction.ENCRYPT_AND_SIGN);
          attributeActionsOnEncrypt.put("firstname", CryptoAction.ENCRYPT_AND_SIGN);
          attributeActionsOnEncrypt.put("lastname", CryptoAction.ENCRYPT_AND_SIGN);
          attributeActionsOnEncrypt.put("last4creditcard", CryptoAction.ENCRYPT_AND_SIGN);
          attributeActionsOnEncrypt.put("expirydate", CryptoAction.ENCRYPT_AND_SIGN);
      
      
          final Map<String, DynamoDbTableEncryptionConfig> tableConfigs = new HashMap<>();
          final DynamoDbTableEncryptionConfig config = DynamoDbTableEncryptionConfig.builder()
                  .logicalTableName(ddbTableName)
                  .partitionKeyName("order_id")
                  .sortKeyName("order_time")
                  .attributeActionsOnEncrypt(attributeActionsOnEncrypt)
                  .keyring(kmsKeyring)
                  .search(SearchConfig.builder()
                          .writeVersion(1) // MUST be 1
                          .versions(beaconVersions)
                          .build())
                  .build();
          tableConfigs.put(ddbTableName, config);
      
          // Create the DynamoDb Encryption Interceptor
          DynamoDbEncryptionInterceptor encryptionInterceptor = DynamoDbEncryptionInterceptor.builder()
                  .config(DynamoDbTablesEncryptionConfig.builder()
                          .tableEncryptionConfigs(tableConfigs)
                          .build())
                  .build();
      
          // Create a new AWS SDK DynamoDb client using the DynamoDb Encryption Interceptor above
          final DynamoDbClient ddb = DynamoDbClient.builder()
                  .overrideConfiguration(
                          ClientOverrideConfiguration.builder()
                                  .addExecutionInterceptor(encryptionInterceptor)
                                  .build())
                  .build();
          return ddb;
      }

  2. Configure beacons: Beacons allow searches on encrypted fields by creating a mapping between the plaintext value of a field and the encrypted value that’s stored in your database. Beacons are generated by DB-ESDK when the data is being encrypted and written by your application. Beacons are stored in your DynamoDB table along with your encrypted data in fields labelled with the prefix aws_dbe_b_.

    It’s important to note that beacons are designed to be implemented in new, unpopulated tables only. If configured on existing tables, beacons will only map to new records that are written and the older records will not have the values populated. There are two types of beacons – standard and compound. The type of beacon you configure determines the type of queries you are able to perform. You should select the type of beacon based on your queries and access patterns:

    • Standard beacons: This beacon type supports querying a single source field using equality operations such as equals and not-equals. It also allows you to query a virtual (conceptual) field by concatenating one or more source fields.
    • Compound beacons: This beacon type supports querying a combination of encrypted and signed or signed-only fields and performs complex operations such as begins with, contains, between, and so on. For compound beacons, you must first build standard beacons on individual fields. Next, you need to create an encrypted part list using a unique prefix for each of the standard beacons. The prefix should be a short value and helps differentiate the individual fields, simplifying the querying process. And last, you build the compound beacon by concatenating the standard beacons that will be used for searching using a split character. Verify that the split character is unique and doesn’t appear in any of the source fields’ data that the compound beacon is constructed from.

    Along with identifying the right beacon type, each beacon must be configured with additional properties such as a unique name, source field, and beacon length. Continuing the previous example, let’s build beacon configurations for the two scenarios that will be demonstrated in this blog post.

    Scenario 1: Identify orders by exact match on the email address.

    In this scenario, search needs to be conducted on a singular attribute using equality operation.

    • Beacon type: Standard beacon.
    • Beacon name: The name can be the same as the encrypted field name, so let’s set it as email.
    • Beacon length: For this example, set the beacon length to 15. For your own uses cases, see Choosing a beacon length.

    Scenario 2: Identify orders using name (first name and last name) and credit card attributes (last four digits and expiry date).

    In this scenario, multiple attributes are required to conduct a search. To satisfy the use case, one option is to create individual compound beacons on name attributes and credit card attributes. However, the name attributes are considered correlated and, as mentioned in the beacon selection guidance, we should avoid building a compound beacon on such correlated fields. Instead in this scenario we will concatenate the attributes and build a virtual field on the name attributes

    • Beacon type: Compound beacon
    • Beacon Configuration:
      • Define a virtual field on firstname and lastname, and label it fullname.
      • Define standard beacons on each of the individual fields that will be used for searching: fullname, last4creditcard, and expirydate. Follow the guidelines for setting standard beacons as explained in Scenario 1.
      • For compound beacons, create an encrypted part list to concatenate the standard beacons with a unique prefix for each of the standard beacons. The prefix helps separate the individual fields. For this example, use C- for the last four digits of the credit card and E- for the expiry date.
      • Build the compound beacons using their respective encrypted part list and a unique split character. For this example, use ~ as the split character.
    • Beacon length: Set beacon length to 15.
    • Beacon Name: Set the compound beacon name as CardCompound.
    private static List<VirtualField> getVirtualField(){
        
        List<VirtualPart> virtualPartList = new ArrayList<>();
        VirtualPart firstnamePart = VirtualPart.builder()
            .loc("firstname")
            .build();
        VirtualPart lastnamePart = VirtualPart.builder()
            .loc("lastname")
            .build();
    
        virtualPartList.add(firstnamePart);
        virtualPartList.add(lastnamePart);
    
        VirtualField fullnameField = VirtualField.builder()
            .name("FullName")
            .parts(virtualPartList)
            .build();
    
        List<VirtualField> virtualFieldList = new ArrayList<>();
        
        virtualFieldList.add(fullnameField);
        return virtualFieldList;
       }
      
      private static List<StandardBeacon> getStandardBeacon(){
    
        List<StandardBeacon> standardBeaconList = new ArrayList<>();
        StandardBeacon emailBeacon = StandardBeacon
          .builder()
          .name("email")
          .length(15)
          .build();
        StandardBeacon last4creditcardBeacon = StandardBeacon
          .builder()
          .name("last4creditcard")
          .length(15)
          .build();
        StandardBeacon expirydateBeacon = StandardBeacon
          .builder()
          .name("expirydate")
          .length(15)
          .build();  
          
      // Virtual field
        StandardBeacon fullnameBeacon = StandardBeacon
          .builder()
          .name("FullName")
          .length(15)
          .build();  
       
        standardBeaconList.add(emailBeacon);
        standardBeaconList.add(fullnameBeacon);
        standardBeaconList.add(last4creditcardBeacon);
        standardBeaconList.add(expirydateBeacon);
        return standardBeaconList;
      }
    
    // Define compound beacon
      private static List<CompoundBeacon> getCompoundBeacon() {
         
       List<EncryptedPart> encryptedPartList_card = new ArrayList<>(); 
        EncryptedPart last4creditcardEncryptedPart = EncryptedPart
          .builder()
          .name("last4creditcard")
          .prefix("C-")
          .build();
          
        EncryptedPart expirydateEncryptedPart = EncryptedPart
          .builder()
          .name("expirydate")
          .prefix("E-")
          .build();  
          
        encryptedPartList_card.add(last4creditcardEncryptedPart);
        encryptedPartList_card.add(expirydateEncryptedPart);
    
        List<CompoundBeacon> compoundBeaconList = new ArrayList<>();
    
        CompoundBeacon CardCompoundBeacon = CompoundBeacon
          .builder()
          .name("CardCompound")
          .split("~")
          .encrypted(encryptedPartList_card)
          .build();      
    
        compoundBeaconList.add(CardCompoundBeacon);
        return compoundBeaconList;  }
    
    // Build the beacons
    private static List<BeaconVersion> getBeaconVersions(List<StandardBeacon> standardBeaconList, List<CompoundBeacon> compoundBeaconList, KeyStore keyStore, String branchKeyId){
        List<BeaconVersion> beaconVersions = new ArrayList<>();
        beaconVersions.add(
                BeaconVersion.builder()
                        .standardBeacons(standardBeaconList)
                        .compoundBeacons(compoundBeaconList)
                        .version(1) // MUST be 1
                        .keyStore(keyStore)
                        .keySource(BeaconKeySource.builder()
                                .single(SingleKeyStore.builder()
                                        .keyId(branchKeyId)
                                        .cacheTTL(6000)
                                        .build())
                                .build())
                        .build()
        );
        return beaconVersions;
    }

  3. Define index: Following DynamoDB best practices, secondary indexes are often essential to support query patterns. DB-ESDK performs searches on the encrypted fields by doing a look up on the fields with matching beacon values. Therefore, if you need to query an encrypted field, you must create an index on the corresponding beacon fields generated by the DB-ESDK library (attributes with prefix aws_dbe_b_), which will be used by your application for searches.

    For this step, you will manually create a global secondary index (GSI).

    Scenario 1: Create a GSI with aws_dbe_b_email as the partition key and leave the sort key empty. Set the index name as aws_dbe_b_email-index. This will allow searches using the email address attribute.

    Scenario 2: Create a GSI with aws_dbe_b_FullName as the partition key and aws_dbe_b_CardCompound as the sort key. Set the index name as aws_dbe_b_VirtualNameCardCompound-index. This will allow searching based on firstname, lastname, last four digits of the credit card, and the expiry date. At this point the required DynamoDB table setup is complete.

Set up the application to insert and query data

Now that the setup is complete, you can use the DB-ESDK from your application to insert new items into your DynamoDB table. DB-ESDK will automatically fetch the data key from the keyring, perform encryption locally, and then make the put call to DynamoDB. By using beacon fields, the application can perform searches on the encrypted fields.

  1. Keyring initialization: Initialize the AWS KMS hierarchical keyring.
    //Retrieve keystore object required for keyring initialization
    private static KeyStore getKeystore(
        String branchKeyDdbTableName,
        String logicalBranchKeyDdbTableName,
        String branchKeyWrappingKmsKeyArn
      ) {
        KeyStore keyStore = KeyStore
          .builder()
          .KeyStoreConfig(
            KeyStoreConfig
              .builder()
              .kmsClient(KmsClient.create())
              .ddbClient(DynamoDbClient.create())
              .ddbTableName(branchKeyDdbTableName)
              .logicalKeyStoreName(logicalBranchKeyDdbTableName)
              .kmsConfiguration(
                KMSConfiguration
                  .builder()
                  .kmsKeyArn(branchKeyWrappingKmsKeyArn)
                  .build()
              )
              .build()
          )
          .build();
        return keyStore;
      }
    
    //Initialize keyring
    private static IKeyring getKeyRing(String branchKeyId, KeyStore keyStore){
        final MaterialProviders matProv = MaterialProviders.builder()
                .MaterialProvidersConfig(MaterialProvidersConfig.builder().build())
                .build();
        CreateAwsKmsHierarchicalKeyringInput keyringInput = CreateAwsKmsHierarchicalKeyringInput.builder()
                .branchKeyId(branchKeyId)
                .keyStore(keyStore)
                .ttlSeconds(60)
                .build();
        final IKeyring kmsKeyring = matProv.CreateAwsKmsHierarchicalKeyring(keyringInput);
      
        return kmsKeyring;
    }

  2. Insert source data: For illustration purpose, lets define a method to load sample data into the OrderInfo table. By using DB-ESDK, the application will encrypt data attributes as defined in the DynamoDB table configuration steps.
    // Insert Order Data
      private static void insertOrder(HashMap<String, AttributeValue> order, DynamoDbClient ddb, String ddbTableName) {
    
        final PutItemRequest putRequest = PutItemRequest.builder()
            .tableName(ddbTableName)
            .item(order)
            .build();
    
        final PutItemResponse putResponse = ddb.putItem(putRequest);
        assert 200 == putResponse.sdkHttpResponse().statusCode();
      }
      
        private static HashMap<String, AttributeValue> getOrder(
        String orderId,
        String orderTime,
        String firstName,
        String lastName,
        String email,
        String last4creditcard,
        String expirydate
      ) 
      {
        final HashMap<String, AttributeValue> order = new HashMap<>();
        order.put("order_id", AttributeValue.builder().s(orderId).build());
        order.put("order_time", AttributeValue.builder().s(orderTime).build());
        order.put("firstname", AttributeValue.builder().s(firstName).build());
        order.put("lastname", AttributeValue.builder().s(lastName).build());
        order.put("email", AttributeValue.builder().s(email).build());
        order.put("last4creditcard", AttributeValue.builder().s(last4creditcard).build());
        order.put("expirydate", AttributeValue.builder().s(expirydate).build());
    
        return order;
      }

  3. Query Data: Define a method to query data using plaintext values

    Scenario 1: Identify orders associated with email address [email protected]. This query should return Order ID ABC-1001.

    private static void runQueryEmail(DynamoDbClient ddb, String ddbTableName) {
        Map<String, String> expressionAttributesNames = new HashMap<>();
        expressionAttributesNames.put("#e", "email");
    
        Map<String, AttributeValue> expressionAttributeValues = new HashMap<>();
        expressionAttributeValues.put(
          ":e",
          AttributeValue.builder().s("[email protected]").build()
        );
    
        QueryRequest queryRequest = QueryRequest
          .builder()
          .tableName(ddbTableName)
          .indexName("aws_dbe_b_email-index")
          .keyConditionExpression("#e = :e")
          .expressionAttributeNames(expressionAttributesNames)
          .expressionAttributeValues(expressionAttributeValues)
          .build();
    
        final QueryResponse queryResponse = ddb.query(queryRequest);
        assert 200 == queryResponse.sdkHttpResponse().statusCode();
    
        List<Map<String, AttributeValue>> items = queryResponse.items();
    
        for (Map<String, AttributeValue> returnedItem : items) {
          System.out.println(returnedItem.get("order_id").s());
        }
      }

    Scenario 2: Identify orders that were placed by John Doe using a specific credit card with the last four digits of 4567 and expiry date of 082026. This query should return Order ID ABC-1003 and ABC-1004.

    private static void runQueryNameCard(DynamoDbClient ddb, String ddbTableName) {
        Map<String, String> expressionAttributesNames = new HashMap<>();
        expressionAttributesNames.put("#PKName", "FullName");
        expressionAttributesNames.put("#SKName", "CardCompound");
    
    
       Map<String, AttributeValue> expressionAttributeValues = new HashMap<>();
        expressionAttributeValues.put(
          ":PKValue",
          AttributeValue.builder().s("JohnDoe").build()
          );
        expressionAttributeValues.put(
          ":SKValue",
          AttributeValue.builder().s("C-4567~E-082026").build()
          ); 
        
        QueryRequest queryRequest = QueryRequest
          .builder()
          .tableName(ddbTableName)
          .indexName("aws_dbe_b_VirtualNameCardCompound-index")
          .keyConditionExpression("#PKName = :PKValue and #SKName = :SKValue")
          .expressionAttributeNames(expressionAttributesNames)
          .expressionAttributeValues(expressionAttributeValues)
          .build();
        final QueryResponse queryResponse = ddb.query(queryRequest);
    
        // Validate query was returned successfully
        assert 200 == queryResponse.sdkHttpResponse().statusCode();
    
        List<Map<String, AttributeValue>> items = queryResponse.items();
    
        for (Map<String, AttributeValue> returnedItem : items) {
          System.out.println(returnedItem.get("order_id").s());
        }
      }

    Note: Compound beacons support complex string operation such as begins_with. In Scenario 2, if you had only the name attributes and last four digits of the credit card, you could still use the compound beacon for querying. You can set the values as shown below to query the beacon using the same code:

    PKValue = “JohnDoe”
    SKValue = "C-4567”
    keyConditionExpression = "#PKName = :PKValue and begins_with(#SKName, :SKValue)"

Now that you have the building blocks, let’s bring this all together and run the following steps to set up the application. For this example, a few of the input parameters have been hard coded. In your application code, replace <KMS key ARN> and <branch-key-id derived from keystore table> from Step 1 and Step 3 mentioned in the Configure DB-ESDK cryptography sections.

//Hard coded values for illustration
String keyStoreTableName = "tblKeyStore";
String logicalKeyStoreName = "lglKeyStore";
String kmsKeyArn = "<KMS key ARN>";
String ddbTableName = "OrderInfo";
String branchKeyId = "<branch-key-id derived from keystore table>";
String branchKeyWrappingKmsKeyArn = "<KMS key ARN>";
String branchKeyDdbTableName = keyStoreTableName;


//run only once to setup keystore 
keyStoreCreateTable(keyStoreTableName, logicalKeyStoreName, kmsKeyArn);

//run only once to create branch and beacon key
keyStoreCreateKey(keyStoreTableName, logicalKeyStoreName, kmsKeyArn);

//run configuration per DynamoDb table 
List<VirtualField> virtualField = getVirtualField();
List<StandardBeacon> beacon = getStandardBeacon ();
List<CompoundBeacon> compoundBeacon = getCompoundBeacon();
KeyStore keyStore = getKeystore(branchKeyDdbTableName, logicalKeyStoreName, branchKeyWrappingKmsKeyArn);
List<BeaconVersion> beaconVersions = getBeaconVersions(beacon, compoundBeacon, keyStore, branchKeyId);
IKeyring keyRing = getKeyRing(branchKeyId, keyStore);
DynamoDbClient ddb = configDDBTable(ddbTableName, keyRing, beaconVersions);

//insert sample records
    HashMap<String, AttributeValue> order1 = getOrder("ABC-1001", "1672531200", "Mary", "Major", "[email protected]", "1234", "012001");
    HashMap<String, AttributeValue> order2 = getOrder("ABC-1002", "1672531400", "John", "Doe", "[email protected]", "1111", "122023");
    HashMap<String, AttributeValue> order3 = getOrder("ABC-1003", "1672531500", "John", "Doe", "[email protected]","4567", "082026");
    HashMap<String, AttributeValue> order4 = getOrder("ABC-1004", "1672531600", "John", "Doe", "[email protected]","4567", "082026");

   insertOrder(order1, ddb, ddbTableName);
   insertOrder(order2, ddb, ddbTableName);
   insertOrder(order3, ddb, ddbTableName);
   insertOrder(order4, ddb, ddbTableName);

//Query OrderInfo table
runQueryEmail(ddb, ddbTableName); //returns orderid ABC-1001
runQueryNameCard(ddb, ddbTableName); // returns orderid ABC-1003, ABC-1004

Conclusion

You’ve just seen how to build an application that encrypts sensitive data on client side, stores it in a DynamoDB table and performs queries on the encrypted data transparently to the application code without decrypting the entire data set. This allows your applications to realize the full potential of the encrypted data while adhering to security and compliance requirements. The code snippet used in this blog is available for reference on GitHub. You can further read the documentation of the AWS Database Encryption SDK and reference the source code at this repository. We encourage you to explore other examples of searching on encrypted fields referenced in this GitHub repository.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Samit Kumbhani

Samit Kumbhani

Samit is an AWS Sr. Solutions Architect in the New York City area. He has 18 years of experience building applications and focuses on Analytics, Business Intelligence, and Databases. He enjoys working with customers to understand and solve their challenges by creating innovative solutions using AWS services. Samit enjoys playing cricket, traveling, and biking.

Author

Nir Ozeri

Nir is a Solutions Architect Manager with Amazon Web Services, based out of New York City. Nir specializes in application modernization, application delivery, and mobile architecture.

Yuri Duchovny

Yuri Duchovny

Yuri is a New York–based Principal Solutions Architect specializing in cloud security, identity, and compliance. He supports cloud transformations at large enterprises, helping them make optimal technology and organizational decisions. Prior to his AWS role, Yuri’s areas of focus included application and networking security, DoS, and fraud protection. Outside of work, he enjoys skiing, sailing, and traveling the world.

Deploy CloudFormation Hooks to an Organization with service-managed StackSets

Post Syndicated from Kirankumar Chandrashekar original https://aws.amazon.com/blogs/devops/deploy-cloudformation-hooks-to-an-organization-with-service-managed-stacksets/

This post demonstrates using AWS CloudFormation StackSets to deploy CloudFormation Hooks from a centralized delegated administrator account to all accounts within an Organization Unit(OU). It provides step-by-step guidance to deploy controls at scale to your AWS Organization as Hooks using StackSets. By following this post, you will learn how to deploy a hook to hundreds of AWS accounts in minutes.

AWS CloudFormation StackSets help deploy CloudFormation stacks to multiple accounts and regions with a single operation. Using service-managed permissions, StackSets automatically generate the IAM roles required to deploy stack instances, eliminating the need for manual creation in each target account prior to deployment. StackSets provide auto-deploy capabilities to deploy stacks to new accounts as they’re added to an Organizational Unit (OU) in AWS Organization. With StackSets, you can deploy AWS well-architected multi-account solutions organization-wide in a single click and target stacks to selected accounts in OUs. You can also leverage StackSets to auto deploy foundational stacks like networking, policies, security, monitoring, disaster recovery, billing, and analytics to new accounts. This ensures consistent security and governance reflecting AWS best practices.

AWS CloudFormation Hooks allow customers to invoke custom logic to validate resource configurations before a CloudFormation stack create/update/delete operation. This helps enforce infrastructure-as-code policies by preventing non-compliant resources. Hooks enable policy-as-code to support consistency and compliance at scale. Without hooks, controlling CloudFormation stack operations centrally across accounts is more challenging because governance checks and enforcement have to be implemented through disjointed workarounds across disparate services after the resources are deployed. Other options like Config rules evaluate resource configurations on a timed basis rather than on stack operations. And SCPs manage account permissions but don’t include custom logic tailored to granular resource configurations. In contrast, CloudFormation hooks allows customer-defined automation to validate each resource as new stacks are deployed or existing ones updated. This enables stronger compliance guarantees and rapid feedback compared to asynchronous or indirect policy enforcement via other mechanisms.

Follow the later sections of this post that provide a step-by-step implementation for deploying hooks across accounts in an organization unit (OU) with a StackSet including:

  1. Configure service-managed permissions to automatically create IAM roles
  2. Create the StackSet in the delegated administrator account
  3. Target the OU to distribute hook stacks to member accounts

This shows how to easily enable a policy-as-code framework organization-wide.

I will show you how to register a custom CloudFormation hook as a private extension, restricting permissions and usage to internal administrators and automation. Registering the hook as a private extension limits discoverability and access. Only approved accounts and roles within the organization can invoke the hook, following security best practices of least privilege.

StackSets Architecture

As depicted in the following AWS StackSets architecture diagram, a dedicated Delegated Administrator Account handles creation, configuration, and management of the StackSet that defines the template for standardized provisioning. In addition, these centrally managed StackSets are deploying a private CloudFormation hook into all member accounts that belong to the given Organization Unit. Registering this as a private CloudFormation hook enables administrative control over the deployment lifecycle events it can respond to. Private hooks prevent public usage, ensuring the hook can only be invoked by approved accounts, roles, or resources inside your organization.

Architecture for deploying CloudFormation Hooks to accounts in an Organization

Diagram 1: StackSets Delegated Administration and Member Account Diagram

In the above architecture, Member accounts join the StackSet through their inclusion in a central Organization Unit. By joining, these accounts receive deployed instances of the StackSet template which provisions resources consistently across accounts, including the controlled private hook for administrative visibility and control.

The delegation of StackSet administration responsibilities to the Delegated Admin Account follows security best practices. Rather than having the sensitive central Management Account handle deployment logistics, delegation isolates these controls to an admin account with purpose-built permissions. The Management Account representing the overall AWS Organization focuses more on high-level compliance governance and organizational oversight. The Delegated Admin Account translates broader guardrails and policies into specific infrastructure automation leveraging StackSets capabilities. This separation of duties ensures administrative privileges are restricted through delegation while also enabling an organization-wide StackSet solution deployment at scale.

Centralized StackSets facilitate account governance through code-based infrastructure management rather than manual account-by-account changes. In summary, the combination of account delegation roles, StackSet administration, and joining through Organization Units creates an architecture to allow governed, infrastructure-as-code deployments across any number of accounts in an AWS Organization.

Sample Hook Development and Deployment

In the section, we will develop a hook on a workstation using the AWS CloudFormation CLI, package it, and upload it to the Hook Package S3 Bucket. Then we will deploy a CloudFormation stack that in turn deploys a hook across member accounts within an Organization Unit (OU) using StackSets.

The sample hook used in this blog post enforces that server-side encryption must be enabled for any S3 buckets and SQS queues created or updated on a CloudFormation stack. This policy requires that all S3 buckets and SQS queues be configured with server-side encryption when provisioned, ensuring security is built into our infrastructure by default. By enforcing encryption at the CloudFormation level, we prevent data from being stored unencrypted and minimize risk of exposure. Rather than manually enabling encryption post-resource creation, our developers simply enable it as a basic CloudFormation parameter. Adding this check directly into provisioning stacks leads to a stronger security posture across environments and applications. This example hook demonstrates functionality for mandating security best practices on infrastructure-as-code deployments.

Prerequisites

On the AWS Organization:

On the workstation where the hooks will be developed:

In the Delegated Administrator account:

Create a hooks package S3 bucket within the delegated administrator account. Upload the hooks package and CloudFormation templates that StackSets will deploy. Ensure the S3 bucket policy allows access from the AWS accounts within the OU. This access lets AWS CloudFormation access the hooks package objects and CloudFormation template objects in the S3 bucket from the member accounts during stack deployment.

Follow these steps to deploy a CloudFormation template that sets up the S3 bucket and permissions:

  1. Click here to download the admin-cfn-hook-deployment-s3-bucket.yaml template file in to your local workstation.
    Note: Make sure you model the S3 bucket and IAM policies as least privilege as possible. For the above S3 Bucket policy, you can add a list of IAM Role ARNs created by the StackSets service managed permissions instead of AWS: “*”, which allows S3 bucket access to all the IAM entities from the accounts in the OU. The ARN of this role will be “arn:aws:iam:::role/stacksets-exec-” in every member account within the OU. For more information about equipping least privilege access to IAM policies and S3 Bucket Policies, refer IAM Policies and Bucket Policies and ACLs! Oh, My! (Controlling Access to S3 Resources) blog post.
  2. Execute the following command to deploy the template admin-cfn-hook-deployment-s3-bucket.yaml using AWS CLI. For more information see Creating a stack using the AWS Command Line Interface. If using AWS CloudFormation console, see Creating a stack on the AWS CloudFormation console.
    To get the OU Id, see Viewing the details of an OU. OU Id starts with “ou-“. To get the Organization Id, see Viewing details about your organization. Organization Id starts with “o-”

    aws cloudformation create-stack \
    --stack-name hooks-asset-stack \
    --template-body file://admin-cfn-deployment-s3-bucket.yaml \
    --parameters ParameterKey=OrgId,ParameterValue="&lt;Org_id&gt;" \
    ParameterKey=OUId,ParameterValue="&lt;OU_id&gt;"
  3. After deploying the stack, note down the AWS S3 bucket name from the CloudFormation Outputs.

Hook Development

In this section, you will develop a sample CloudFormation hook package that will enforce encryption for S3 Buckets and SQS queues within the preCreate and preDelete hook. Follow the steps in the walkthrough to develop a sample hook and generate a zip package for deploying and enabling them in all the accounts within an OU. While following the walkthrough, within the Registering hooks section, make sure that you stop right after executing the cfn submit --dry-run command. The --dry-run option will make sure that your hook is built and packaged your without registering it with CloudFormation on your account. While initiating a Hook project if you created a new directory with the name mycompany-testing-mytesthook, the hook package will be generated as a zip file with the name mycompany-testing-mytesthook.zip at the root your hooks project.

Upload mycompany-testing-mytesthook.zip file to the hooks package S3 bucket within the Delegated Administrator account. The packaged zip file can then be distributed to enable the encryption hooks across all accounts in the target OU.

Note: If you are using your own hooks project and not doing the tutorial, irrespective of it, you should make sure that you are executing the cfn submit command with the --dry-run option. This ensures you have a hooks package that can be distributed and reused across multiple accounts.

Hook Deployment using CloudFormation Stack Sets

In this section, deploy the sample hook developed previously across all accounts within an OU. Use a centralized CloudFormation stack deployed from the delegated administrator account via StackSets.

Deploying hooks via CloudFormation requires these key resources:

  1. AWS::CloudFormation::HookVersion: Publishes a new hook version to the CloudFormation registry
  2. AWS::CloudFormation::HookDefaultVersion: Specifies the default hook version for the AWS account and region
  3. AWS::CloudFormation::HookTypeConfig: Defines the hook configuration
  4. AWS::IAM::Role #1: Task execution role that grants the hook permissions
  5. AWS::IAM::Role #2: (Optional) role for CloudWatch logging that CloudFormation will assume to send log entries during hook execution
  6. AWS::Logs::LogGroup: (Optional) Enables CloudWatch error logging for hook executions

Follow these steps to deploy CloudFormation Hooks to accounts within the OU using StackSets:

  1. Click here to download the hooks-template.yaml template file into your local workstation and upload it into the Hooks package S3 bucket in the Delegated Administrator account.
  2. Deploy the hooks CloudFormation template hooks-template.yaml to all accounts within an OU using StackSets. Leverage service-managed permissions for automatic IAM role creation across the OU.
    To deploy the hooks template hooks-template.yaml across OU using StackSets, click here to download the CloudFormation StackSets template hooks-stack-sets-template.yaml locally, and upload it to the hooks package S3 bucket in the delegated administrator account. This StackSets template contains an AWS::CloudFormation::StackSet resource that will deploy the necessary hooks resources from hooks-template.yaml to all accounts in the target OU. Using SERVICE_MANAGED permissions model automatically handle provisioning the required IAM execution roles per account within the OU.
  3. Execute the following command to deploy the template hooks-stack-sets-template.yaml using AWS CLI. For more information see Creating a stack using the AWS Command Line Interface. If using AWS CloudFormation console, see Creating a stack on the AWS CloudFormation console.To get the S3 Https URL for the hooks template, hooks package and StackSets template, login to the AWS S3 service on the AWS console, select the respective object and click on Copy URL button as shown in the following screenshot:s3 download https url
    Diagram 2: S3 Https URL

    To get the OU Id, see Viewing the details of an OU. OU Id starts with “ou-“.
    Make sure to replace the <S3BucketName> and then <OU_Id> accordingly in the following command:

    aws cloudformation create-stack --stack-name hooks-stack-set-stack \
    --template-url https://<S3BucketName>.s3.us-west-2.amazonaws.com/hooks-stack-sets-template.yaml \
    --parameters ParameterKey=OuId,ParameterValue="<OU_Id>" \
    ParameterKey=HookTypeName,ParameterValue="MyCompany::Testing::MyTestHook" \
    ParameterKey=s3TemplateURL,ParameterValue="https://<S3BucketName>.s3.us-west-2.amazonaws.com/hooks-template.yaml" \
    ParameterKey=SchemaHandlerPackageS3URL,ParameterValue="https://<S3BucketName>.s3.us-west-2.amazonaws.com/mycompany-testing-mytesthook.zip"
  4. Check the progress of the stack deployment using the aws cloudformation describe-stack command. Move to the next section when the stack status is CREATE_COMPLETE.
    aws cloudformation describe-stacks --stack-name hooks-stack-set-stack
  5. If you navigate to the AWS CloudFormation Service’s StackSets section in the console, you can view the stack instances deployed to the accounts within the OU. Alternatively, you can execute the AWS CloudFormation list-stack-instances CLI command below to list the deployed stack instances:
    aws cloudformation list-stack-instances --stack-set-name MyTestHookStackSet

Testing the deployed hook

Deploy the following sample templates into any AWS account that is within the OU where the hooks was deployed and activated. Follow the steps in the Creating a stack on the AWS CloudFormation console. If using AWS CloudFormation CLI, follow the steps in the Creating a stack using the AWS Command Line Interface.

  1. Provision a non-compliant stack without server-side encryption using the following template:
    AWSTemplateFormatVersion: 2010-09-09
    Description: |
      This CloudFormation template provisions an S3 Bucket
    Resources:
      S3Bucket:
        Type: 'AWS::S3::Bucket'
        Properties: {}

    The stack deployment will not succeed and will give the following error message

    The following hook(s) failed: [MyCompany::Testing::MyTestHook] and the hook status reason as shown in the following screenshot:

    stack deployment failure due to hooks execution
    Diagram 3: S3 Bucket creation failure with hooks execution

  2. Provision a stack using the following template that has server-side encryption for the S3 Bucket.
    AWSTemplateFormatVersion: 2010-09-09
    Description: |
      This CloudFormation template provisions an encrypted S3 Bucket. **WARNING** This template creates an Amazon S3 bucket and a KMS key that you will be charged for. You will be billed for the AWS resources used if you create a stack from this template.
    Resources:
      EncryptedS3Bucket:
        Type: "AWS::S3::Bucket"
        Properties:
          BucketName: !Sub "encryptedbucket-${AWS::Region}-${AWS::AccountId}"
          BucketEncryption:
            ServerSideEncryptionConfiguration:
              - ServerSideEncryptionByDefault:
                  SSEAlgorithm: "aws:kms"
                  KMSMasterKeyID: !Ref EncryptionKey
                BucketKeyEnabled: true
      EncryptionKey:
        Type: "AWS::KMS::Key"
        DeletionPolicy: Retain
        UpdateReplacePolicy: Retain
        Properties:
          Description: KMS key used to encrypt the resource type artifacts
          EnableKeyRotation: true
          KeyPolicy:
            Version: 2012-10-17
            Statement:
              - Sid: Enable full access for owning account
                Effect: Allow
                Principal:
                  AWS: !Ref "AWS::AccountId"
                Action: "kms:*"
                Resource: "*"
    Outputs:
      EncryptedBucketName:
        Value: !Ref EncryptedS3Bucket

    The deployment will succeed as it will pass the hook validation with the following hook status reason as shown in the following screenshot:

    stack deployment pass due to hooks executionDiagram 4: S3 Bucket creation success with hooks execution

Updating the hooks package

To update the hooks package, follow the same steps described in the Hooks Development section to change the hook code accordingly. Then, execute the cfn submit --dry-run command to build and generate the hooks package file with the registering the type with the CloudFormation registry. Make sure to rename the zip file with a unique name compared to what was previously used. Otherwise, while updating the CloudFormation StackSets stack, it will not see any changes in the template and thus not deploy updates. The best practice is to use a CI/CD pipeline to manage the hook package. Typically, it is good to assign unique version numbers to the hooks packages so that CloudFormation stacks with the new changes get deployed.

Cleanup

Navigate to the AWS CloudFormation console on the Delegated Administrator account, and note down the Hooks package S3 bucket name and empty its contents. Refer to Emptying the Bucket for more information.

Delete the CloudFormation stacks in the following order:

  1. Test stack that failed
  2. Test stack that passed
  3. StackSets CloudFormation stack. This has a DeletionPolicy set to Retain, update the stack by removing the DeletionPolicy and then initiate a stack deletion via CloudFormation or physically delete the StackSet instances and StackSets from the Console or CLI by following: 1. Delete stack instances from your stack set 2. Delete a stack set
  4. Hooks asset CloudFormation stack

Refer to the following documentation to delete CloudFormation Stacks: Deleting a stack on the AWS CloudFormation console or Deleting a stack using AWS CLI.

Conclusion

Throughout this blog post, you have explored how AWS StackSets enable the scalable and centralized deployment of CloudFormation hooks across all accounts within an Organization Unit. By implementing hooks as reusable code templates, StackSets provide consistency benefits and slash the administrative labor associated with fragmented and manual installs. As organizations aim to fortify governance, compliance, and security through hooks, StackSets offer a turnkey mechanism to efficiently reach hundreds of accounts. By leveraging the described architecture of delegated StackSet administration and member account joining, organizations can implement a single hook across hundreds of accounts rather than manually enabling hooks per account. Centralizing your hook code-base within StackSets templates facilitates uniform adoption while also simplifying maintenance. Administrators can update hooks in one location instead of attempting fragmented, account-by-account changes. By enclosing new hooks within reusable StackSets templates, administrators benefit from infrastructure-as-code descriptiveness and version control instead of one-off scripts. Once configured, StackSets provide automated hook propagation without overhead. The delegated administrator merely needs to include target accounts through their Organization Unit alignment rather than handling individual permissions. New accounts added to the OU automatically receive hook deployments through the StackSet orchestration engine.

About the Author

kirankumar.jpeg

Kirankumar Chandrashekar is a Sr. Solutions Architect for Strategic Accounts at AWS. He focuses on leading customers in architecting DevOps, modernization using serverless, containers and container orchestration technologies like Docker, ECS, EKS to name a few. Kirankumar is passionate about DevOps, Infrastructure as Code, modernization and solving complex customer issues. He enjoys music, as well as cooking and traveling.

Enforce fine-grained access control on Open Table Formats via Amazon EMR integrated with AWS Lake Formation

Post Syndicated from Raymond Lai original https://aws.amazon.com/blogs/big-data/enforce-fine-grained-access-control-on-open-table-formats-via-amazon-emr-integrated-with-aws-lake-formation/

With Amazon EMR 6.15, we launched AWS Lake Formation based fine-grained access controls (FGAC) on Open Table Formats (OTFs), including Apache Hudi, Apache Iceberg, and Delta lake. This allows you to simplify security and governance over transactional data lakes by providing access controls at table-, column-, and row-level permissions with your Apache Spark jobs. Many large enterprise companies seek to use their transactional data lake to gain insights and improve decision-making. You can build a lake house architecture using Amazon EMR integrated with Lake Formation for FGAC. This combination of services allows you to conduct data analysis on your transactional data lake while ensuring secure and controlled access.

The Amazon EMR record server component supports table-, column-, row-, cell-, and nested attribute-level data filtering functionality. It extends support to Hive, Apache Hudi, Apache Iceberg, and Delta lake formats for both reading (including time travel and incremental query) and write operations (on DML statements such as INSERT). Additionally, with version 6.15, Amazon EMR introduces access control protection for its application web interface such as on-cluster Spark History Server, Yarn Timeline Server, and Yarn Resource Manager UI.

In this post, we demonstrate how to implement FGAC on Apache Hudi tables using Amazon EMR integrated with Lake Formation.

Transaction data lake use case

Amazon EMR customers often use Open Table Formats to support their ACID transaction and time travel needs in a data lake. By preserving historical versions, data lake time travel provides benefits such as auditing and compliance, data recovery and rollback, reproducible analysis, and data exploration at different points in time.

Another popular transaction data lake use case is incremental query. Incremental query refers to a query strategy that focuses on processing and analyzing only the new or updated data within a data lake since the last query. The key idea behind incremental queries is to use metadata or change tracking mechanisms to identify the new or modified data since the last query. By identifying these changes, the query engine can optimize the query to process only the relevant data, significantly reducing the processing time and resource requirements.

Solution overview

In this post, we demonstrate how to implement FGAC on Apache Hudi tables using Amazon EMR on Amazon Elastic Compute Cloud (Amazon EC2) integrated with Lake Formation. Apache Hudi is an open source transactional data lake framework that greatly simplifies incremental data processing and the development of data pipelines. This new FGAC feature supports all OTF. Besides demonstrating with Hudi here, we will follow up with other OTF tables with other blogs. We use notebooks in Amazon SageMaker Studio to read and write Hudi data via different user access permissions through an EMR cluster. This reflects real-world data access scenarios—for example, if an engineering user needs full data access to troubleshoot on a data platform, whereas data analysts may only need to access a subset of that data that doesn’t contain personally identifiable information (PII). Integrating with Lake Formation via the Amazon EMR runtime role further enables you to improve your data security posture and simplifies data control management for Amazon EMR workloads. This solution ensures a secure and controlled environment for data access, meeting the diverse needs and security requirements of different users and roles in an organization.

The following diagram illustrates the solution architecture.

Solution architecture

We conduct a data ingestion process to upsert (update and insert) a Hudi dataset to an Amazon Simple Storage Service (Amazon S3) bucket, and persist or update the table schema in the AWS Glue Data Catalog. With zero data movement, we can query the Hudi table governed by Lake Formation via various AWS services, such as Amazon Athena, Amazon EMR, and Amazon SageMaker.

When users submit a Spark job through any EMR cluster endpoints (EMR Steps, Livy, EMR Studio, and SageMaker), Lake Formation validates their privileges and instructs the EMR cluster to filter out sensitive data such as PII data.

This solution has three different types of users with different levels of permissions to access the Hudi data:

  • hudi-db-creator-role – This is used by the data lake administrator who has privileges to carry out DDL operations such as creating, modifying, and deleting database objects. They can define data filtering rules on Lake Formation for row-level and column-level data access control. These FGAC rules ensure that data lake is secured and fulfills the data privacy regulations required.
  • hudi-table-pii-role – This is used by engineering users. The engineering users are capable of carrying out time travel and incremental queries on both Copy-on-Write (CoW) and Merge-on-Read (MoR). They also have privilege to access PII data based on any timestamps.
  • hudi-table-non-pii-role – This is used by data analysts. Data analysts’ data access rights are governed by FGAC authorized rules controlled by data lake administrators. They do not have visibility on columns containing PII data like names and addresses. Additionally, they can’t access rows of data that don’t fulfill certain conditions. For example, the users only can access data rows that belong to their country.

Prerequisites

You can download the three notebooks used in this post from the GitHub repo.

Before you deploy the solution, make sure you have the following:

Complete the following steps to set up your permissions:

  1. Log in to your AWS account with your admin IAM user.

Make sure you are in theus-east-1Region.

  1. Create a S3 bucket in the us-east-1 Region (for example,emr-fgac-hudi-us-east-1-<ACCOUNT ID>).

Next, we enable Lake Formation by changing the default permission model.

  1. Sign in to the Lake Formation console as the administrator user.
  2. Choose Data Catalog settings under Administration in the navigation pane.
  3. Under Default permissions for newly created databases and tables, deselect Use only IAM access control for new databases and Use only IAM access control for new tables in new databases.
  4. Choose Save.

Data Catalog settings

Alternatively, you need to revoke IAMAllowedPrincipals on resources (databases and tables) created if you started Lake Formation with the default option.

Finally, we create a key pair for Amazon EMR.

  1. On the Amazon EC2 console, choose Key pairs in the navigation pane.
  2. Choose Create key pair.
  3. For Name, enter a name (for exampleemr-fgac-hudi-keypair).
  4. Choose Create key pair.

Create key pair

The generated key pair (for this post, emr-fgac-hudi-keypair.pem) will save to your local computer.

Next, we create an AWS Cloud9 interactive development environment (IDE).

  1. On the AWS Cloud9 console, choose Environments in the navigation pane.
  2. Choose Create environment.
  3. For Name¸ enter a name (for example,emr-fgac-hudi-env).
  4. Keep the other settings as default.

Cloud9 environment

  1. Choose Create.
  2. When the IDE is ready, choose Open to open it.

cloud9 environment

  1. In the AWS Cloud9 IDE, on the File menu, choose Upload Local Files.

Upload local file

  1. Upload the key pair file (emr-fgac-hudi-keypair.pem).
  2. Choose the plus sign and choose New Terminal.

new terminal

  1. In the terminal, input the following command lines:
#Create encryption certificates for EMR in transit encryption
openssl req -x509 \
-newkey rsa:1024 \
-keyout privateKey.pem \
-out certificateChain.pem \
-days 365 \
-nodes \
-subj '/C=US/ST=Washington/L=Seattle/O=MyOrg/OU=MyDept/CN=*.compute.internal'
cp certificateChain.pem trustedCertificates.pem

# Zip certificates
zip -r -X my-certs.zip certificateChain.pem privateKey.pem trustedCertificates.pem

# Upload the certificates zip file to S3 bucket
# Replace <ACCOUNT ID> with your AWS account ID
aws s3 cp ./my-certs.zip s3://emr-fgac-hudi-us-east-1-<ACCOUNT ID>/my-certs.zip

Note that the example code is a proof of concept for demonstration purposes only. For production systems, use a trusted certification authority (CA) to issue certificates. Refer to Providing certificates for encrypting data in transit with Amazon EMR encryption for details.

Deploy the solution via AWS CloudFormation

We provide an AWS CloudFormation template that automatically sets up the following services and components:

  • An S3 bucket for the data lake. It contains the sample TPC-DS dataset.
  • An EMR cluster with security configuration and public DNS enabled.
  • EMR runtime IAM roles with Lake Formation fine-grained permissions:
    • <STACK-NAME>-hudi-db-creator-role – This role is used to create Apache Hudi database and tables.
    • <STACK-NAME>-hudi-table-pii-role – This role provides permission to query all columns of Hudi tables, including columns with PII.
    • <STACK-NAME>-hudi-table-non-pii-role – This role provides permission to query Hudi tables that have filtered out PII columns by Lake Formation.
  • SageMaker Studio execution roles that allow the users to assume their corresponding EMR runtime roles.
  • Networking resources such as VPC, subnets, and security groups.

Complete the following steps to deploy the resources:

  1. Choose Quick create stack to launch the CloudFormation stack.
  2. For Stack name, enter a stack name (for example,rsv2-emr-hudi-blog).
  3. For Ec2KeyPair, enter the name of your key pair.
  4. For IdleTimeout, enter an idle timeout for the EMR cluster to avoid paying for the cluster when it’s not being used.
  5. For InitS3Bucket, enter the S3 bucket name you created to save the Amazon EMR encryption certificate .zip file.
  6. For S3CertsZip, enter the S3 URI of the Amazon EMR encryption certificate .zip file.

CloudFormation template

  1. Select I acknowledge that AWS CloudFormation might create IAM resources with custom names.
  2. Choose Create stack.

The CloudFormation stack deployment takes around 10 minutes.

Set up Lake Formation for Amazon EMR integration

Complete the following steps to set up Lake Formation:

  1. On the Lake Formation console, choose Application integration settings under Administration in the navigation pane.
  2. Select Allow external engines to filter data in Amazon S3 locations registered with Lake Formation.
  3. Choose Amazon EMR for Session tag values.
  4. Enter your AWS account ID for AWS account IDs.
  5. Choose Save.

LF - Application integration settings

  1. Choose Databases under Data Catalog in the navigation pane.
  2. Choose Create database.
  3. For Name, enter default.
  4. Choose Create database.

LF - create database

  1. Choose Data lake permissions under Permissions in the navigation pane.
  2. Choose Grant.
  3. Select IAM users and roles.
  4. Choose your IAM roles.
  5. For Databases, choose default.
  6. For Database permissions, select Describe.
  7. Choose Grant.

LF - Grant data permissions

Copy Hudi JAR file to Amazon EMR HDFS

To use Hudi with Jupyter notebooks, you need to complete the following steps for the EMR cluster, which includes copying a Hudi JAR file from the Amazon EMR local directory to its HDFS storage, so that you can configure a Spark session to use Hudi:

  1. Authorize inbound SSH traffic (port 22).
  2. Copy the value for Primary node public DNS (for example, ec2-XXX-XXX-XXX-XXX.compute-1.amazonaws.com) from the EMR cluster Summary section.

EMR cluster summary

  1. Go back to previous AWS Cloud9 terminal you used to create the EC2 key pair.
  2. Run the following command to SSH into the EMR primary node. Replace the placeholder with your EMR DNS hostname:
chmod 400 emr-fgac-hudi-keypair.pem
ssh -i emr-fgac-hudi-keypair.pem [email protected]
  1. Run the following command to copy the Hudi JAR file to HDFS:
hdfs dfs -mkdir -p /apps/hudi/lib
hdfs dfs -copyFromLocal /usr/lib/hudi/hudi-spark-bundle.jar /apps/hudi/lib/hudi-spark-bundle.jar

Create the Hudi database and tables in Lake Formation

Now we’re ready to create the Hudi database and tables with FGAC enabled by the EMR runtime role. The EMR runtime role is an IAM role that you can specify when you submit a job or query to an EMR cluster.

Grant database creator permission

First, let’s grant the Lake Formation database creator permission to<STACK-NAME>-hudi-db-creator-role:

  1. Log in to your AWS account as an administrator.
  2. On the Lake Formation console, choose Administrative roles and tasks under Administration in the navigation pane.
  3. Confirm that your AWS login user has been added as a data lake administrator.
  4. In the Database creator section, choose Grant.
  5. For IAM users and roles, choose<STACK-NAME>-hudi-db-creator-role.
  6. For Catalog permissions, select Create database.
  7. Choose Grant.

Register the data lake location

Next, let’s register the S3 data lake location in Lake Formation:

  1. On the Lake Formation console, choose Data lake locations under Administration in the navigation pane.
  2. Choose Register location.
  3. For Amazon S3 path, Choose Browse and choose the data lake S3 bucket. (<STACK_NAME>s3bucket-XXXXXXX) created from the CloudFormation stack.
  4. For IAM role, choose<STACK-NAME>-hudi-db-creator-role.
  5. For Permission mode, select Lake Formation.
  6. Choose Register location.

LF - Register location

Grant data location permission

Next, we need to grant<STACK-NAME>-hudi-db-creator-rolethe data location permission:

  1. On the Lake Formation console, choose Data locations under Permissions in the navigation pane.
  2. Choose Grant.
  3. For IAM users and roles, choose<STACK-NAME>-hudi-db-creator-role.
  4. For Storage locations, enter the S3 bucket (<STACK_NAME>-s3bucket-XXXXXXX).
  5. Choose Grant.

LF - Grant permissions

Connect to the EMR cluster

Now, let’s use a Jupyter notebook in SageMaker Studio to connect to the EMR cluster with the database creator EMR runtime role:

  1. On the SageMaker console, choose Domains in the navigation pane.
  2. Choose the domain<STACK-NAME>-Studio-EMR-LF-Hudi.
  3. On the Launch menu next to the user profile<STACK-NAME>-hudi-db-creator, choose Studio.

SM - Domain details

  1. Download the notebook rsv2-hudi-db-creator-notebook.
  2. Choose the upload icon.

SM Studio - Upload

  1. Choose the downloaded Jupyter notebook and choose Open.
  2. Open the uploaded notebook.
  3. For Image, choose SparkMagic.
  4. For Kernel, choose PySpark.
  5. Leave the other configurations as default and choose Select.

SM Studio - Change environment

  1. Choose Cluster to connect to the EMR cluster.

SM Studio - connect EMR cluster

  1. Choose the EMR on EC2 cluster (<STACK-NAME>-EMR-Cluster) created with the CloudFormation stack.
  2. Choose Connect.
  3. For EMR execution role, choose<STACK-NAME>-hudi-db-creator-role.
  4. Choose Connect.

Create database and tables

Now you can follow the steps in the notebook to create the Hudi database and tables. The major steps are as follows:

  1. When you start the notebook, configure“spark.sql.catalog.spark_catalog.lf.managed":"true"to inform Spark that spark_catalog is protected by Lake Formation.
  2. Create Hudi tables using the following Spark SQL.
%%sql 
CREATE TABLE IF NOT EXISTS ${hudi_catalog}.${hudi_db}.${cow_table_name_sql}(
    c_customer_id string,
    c_birth_country string,
    c_customer_sk integer,
    c_email_address string,
    c_first_name string,
    c_last_name string,
    ts bigint
) USING hudi
LOCATION '${cow_table_location_sql}'
OPTIONS (
  type = 'cow',
  primaryKey = '${hudi_primary_key}',
  preCombineField = '${hudi_pre_combined_field}'
 ) 
PARTITIONED BY (${hudi_partitioin_field});

  1. Insert data from the source table to the Hudi tables.
%%sql
INSERT OVERWRITE ${hudi_catalog}.${hudi_db}.${cow_table_name_sql}
SELECT 
    c_customer_id ,  
    c_customer_sk,
    c_email_address,
    c_first_name,
    c_last_name,
    unix_timestamp(current_timestamp()) AS ts,
    c_birth_country
FROM ${src_df_view}
WHERE c_birth_country = 'HONG KONG' OR c_birth_country = 'CHINA' 
LIMIT 1000
  1. Insert data again into the Hudi tables.
%%sql
INSERT INTO ${hudi_catalog}.${hudi_db}.${cow_table_name_sql}
SELECT 
    c_customer_id ,  
    c_customer_sk,
    c_email_address,
    c_first_name,
    c_last_name,
    unix_timestamp(current_timestamp()) AS ts,
    c_birth_country
FROM ${insert_into_view}

Query the Hudi tables via Lake Formation with FGAC

After you create the Hudi database and tables, you’re ready to query the tables using fine-grained access control with Lake Formation. We have created two types of Hudi tables: Copy-On-Write (COW) and Merge-On-Read (MOR). The COW table stores data in a columnar format (Parquet), and each update creates a new version of files during a write. This means that for every update, Hudi rewrites the entire file, which can be more resource-intensive but provides faster read performance. MOR, on the other hand, is introduced for cases where COW may not be optimal, particularly for write- or change-heavy workloads. In a MOR table, each time there is an update, Hudi writes only the row for the changed record, which reduces cost and enables low-latency writes. However, the read performance might be slower compared to COW tables.

Grant table access permission

We use the IAM role<STACK-NAME>-hudi-table-pii-roleto query Hudi COW and MOR containing PII columns. We first grant the table access permission via Lake Formation:

  1. On the Lake Formation console, choose Data lake permissions under Permissions in the navigation pane.
  2. Choose Grant.
  3. Choose<STACK-NAME>-hudi-table-pii-rolefor IAM users and roles.
  4. Choose thersv2_blog_hudi_db_1database for Databases.
  5. For Tables, choose the four Hudi tables you created in the Jupyter notebook.

LF - Grant data permissions

  1. For Table permissions, select Select.
  2. Choose Grant.

LF - table permissions

Query PII columns

Now you’re ready to run the notebook to query the Hudi tables. Let’s follow similar steps to the previous section to run the notebook in SageMaker Studio:

  1. On the SageMaker console, navigate to the<STACK-NAME>-Studio-EMR-LF-Hudidomain.
  2. On the Launch menu next to the<STACK-NAME>-hudi-table-readeruser profile, choose Studio.
  3. Upload the downloaded notebook rsv2-hudi-table-pii-reader-notebook.
  4. Open the uploaded notebook.
  5. Repeat the notebook setup steps and connect to the same EMR cluster, but use the role<STACK-NAME>-hudi-table-pii-role.

In the current stage, FGAC-enabled EMR cluster needs to query Hudi’s commit time column for performing incremental queries and time travel. It does not support Spark’s “timestamp as of” syntax and Spark.read(). We are actively working on incorporating support for both actions in future Amazon EMR releases with FGAC enabled.

You can now follow the steps in the notebook. The following are some highlighted steps:

  1. Run a snapshot query.
%%sql 
SELECT c_birth_country, count(*) FROM ${hudi_catalog}.${hudi_db}.${cow_table_name_sql} GROUP BY c_birth_country;
  1. Run an incremental query.
incremental_df = spark.sql(f"""
SELECT * FROM {HUDI_CATALOG}.{HUDI_DATABASE}.{COW_TABLE_NAME_SQL} WHERE _hoodie_commit_time >= {commit_ts[-1]}
""")

incremental_df.createOrReplaceTempView("incremental_view")
%%sql
SELECT 
    c_birth_country, 
    count(*) 
FROM incremental_view
GROUP BY c_birth_country;
  1. Run a time travel query.
%%sql
SELECT
    c_birth_country, COUNT(*) as count
FROM ${hudi_catalog}.${hudi_db}.${cow_table_name_sql}
WHERE _hoodie_commit_time IN
(
    SELECT DISTINCT _hoodie_commit_time FROM ${hudi_catalog}.${hudi_db}.${cow_table_name_sql} ORDER BY _hoodie_commit_time LIMIT 1 
)
GROUP BY c_birth_country
  1. Run MOR read-optimized and real-time table queries.
%%sql
SELECT
    a.email_label,
    count(*)
FROM (
    SELECT
        CASE
            WHEN c_email_address = 'UNKNOWN' THEN 'UNKNOWN'
            ELSE 'NOT_UNKNOWN'
        END AS email_label
    FROM ${hudi_catalog}.${hudi_db}.${mor_table_name_sql}_ro
    WHERE c_birth_country = 'HONG KONG'
) a
GROUP BY a.email_label;
%%sql
SELECT *  
FROM ${hudi_catalog}.${hudi_db}.${mor_table_name_sql}_ro
WHERE 
    c_birth_country = 'INDIA' OR c_first_name = 'MASKED'

Query the Hudi tables with column-level and row-level data filters

We use the IAM role<STACK-NAME>-hudi-table-non-pii-roleto query Hudi tables. This role is not allowed to query any columns containing PII. We use the Lake Formation column-level and row-level data filters to implement fine-grained access control:

  1. On the Lake Formation console, choose Data filters under Data Catalog in the navigation pane.
  2. Choose Create new filter.
  3. For Data filter name, entercustomer-pii-filter.
  4. Choosersv2_blog_hudi_db_1for Target database.
  5. Choosersv2_blog_hudi_mor_sql_dl_customer_1for Target table.
  6. Select Exclude columns and choose thec_customer_id,c_email_address, andc_last_namecolumns.
  7. Enterc_birth_country != 'HONG KONG'for Row filter expression.
  8. Choose Create filter.

LF - create data filter

  1. Choose Data lake permissions under Permissions in the navigation pane.
  2. Choose Grant.
  3. Choose<STACK-NAME>-hudi-table-non-pii-rolefor IAM users and roles.
  4. Choosersv2_blog_hudi_db_1for Databases.
  5. Choosersv2_blog_hudi_mor_sql_dl_tpc_customer_1for Tables.
  6. Choosecustomer-pii-filterfor Data filters.
  7. For Data filter permissions, select Select.
  8. Choose Grant.

LF - Grant data permissions

Let’s follow similar steps to run the notebook in SageMaker Studio:

  1. On the SageMaker console, navigate to the domainStudio-EMR-LF-Hudi.
  2. On the Launch menu for thehudi-table-readeruser profile, choose Studio.
  3. Upload the downloaded notebook rsv2-hudi-table-non-pii-reader-notebook and choose Open.
  4. Repeat the notebook setup steps and connect to the same EMR cluster, but select the role<STACK-NAME>-hudi-table-non-pii-role.

You can now follow the steps in the notebook. From the query results, you can see that FGAC via the Lake Formation data filter has been applied. The role can’t see the PII columnsc_customer_id,c_last_name, andc_email_address. Also, the rows fromHONG KONGhave been filtered.

filtered query result

Clean up

After you’re done experimenting with the solution, we recommend cleaning up resources with the following steps to avoid unexpected costs:

  1. Shut down the SageMaker Studio apps for the user profiles.

The EMR cluster will be automatically deleted after the idle timeout value.

  1. Delete the Amazon Elastic File System (Amazon EFS) volume created for the domain.
  2. Empty the S3 buckets created by the CloudFormation stack.
  3. On the AWS CloudFormation console, delete the stack.

Conclusion

In this post, we used Apachi Hudi, one type of OTF tables, to demonstrate this new feature to enforce fine-grained access control on Amazon EMR. You can define granular permissions in Lake Formation for OTF tables and apply them via Spark SQL queries on EMR clusters. You also can use transactional data lake features such as running snapshot queries, incremental queries, time travel, and DML query. Please note that this new feature covers all OTF tables.

This feature is launched starting from Amazon EMR release 6.15 in all Regions where Amazon EMR is available. With the Amazon EMR integration with Lake Formation, you can confidently manage and process big data, unlocking insights and facilitating informed decision-making while upholding data security and governance.

To learn more, refer to Enable Lake Formation with Amazon EMR and feel free to contact your AWS Solutions Architects, who can be of assistance alongside your data journey.


About the Author

Raymond LaiRaymond Lai is a Senior Solutions Architect who specializes in catering to the needs of large enterprise customers. His expertise lies in assisting customers with migrating intricate enterprise systems and databases to AWS, constructing enterprise data warehousing and data lake platforms. Raymond excels in identifying and designing solutions for AI/ML use cases, and he has a particular focus on AWS Serverless solutions and Event Driven Architecture design.

Bin Wang, PhD, is a Senior Analytic Specialist Solutions Architect at AWS, boasting over 12 years of experience in the ML industry, with a particular focus on advertising. He possesses expertise in natural language processing (NLP), recommender systems, diverse ML algorithms, and ML operations. He is deeply passionate about applying ML/DL and big data techniques to solve real-world problems.

Aditya Shah is a Software Development Engineer at AWS. He is interested in Databases and Data warehouse engines and has worked on performance optimisations, security compliance and ACID compliance for engines like Apache Hive and Apache Spark.

Melody Yang is a Senior Big Data Solution Architect for Amazon EMR at AWS. She is an experienced analytics leader working with AWS customers to provide best practice guidance and technical advice in order to assist their success in data transformation. Her areas of interests are open-source frameworks and automation, data engineering and DataOps.

Power neural search with AI/ML connectors in Amazon OpenSearch Service

Post Syndicated from Aruna Govindaraju original https://aws.amazon.com/blogs/big-data/power-neural-search-with-ai-ml-connectors-in-amazon-opensearch-service/

With the launch of the neural search feature for Amazon OpenSearch Service in OpenSearch 2.9, it’s now effortless to integrate with AI/ML models to power semantic search and other use cases. OpenSearch Service has supported both lexical and vector search since the introduction of its k-nearest neighbor (k-NN) feature in 2020; however, configuring semantic search required building a framework to integrate machine learning (ML) models to ingest and search. The neural search feature facilitates text-to-vector transformation during ingestion and search. When you use a neural query during search, the query is translated into a vector embedding and k-NN is used to return the nearest vector embeddings from the corpus.

To use neural search, you must set up an ML model. We recommend configuring AI/ML connectors to AWS AI and ML services (such as Amazon SageMaker or Amazon Bedrock) or third-party alternatives. Starting with version 2.9 on OpenSearch Service, AI/ML connectors integrate with neural search to simplify and operationalize the translation of your data corpus and queries to vector embeddings, thereby removing much of the complexity of vector hydration and search.

In this post, we demonstrate how to configure AI/ML connectors to external models through the OpenSearch Service console.

Solution Overview

Specifically, this post walks you through connecting to a model in SageMaker. Then we guide you through using the connector to configure semantic search on OpenSearch Service as an example of a use case that is supported through connection to an ML model. Amazon Bedrock and SageMaker integrations are currently supported on the OpenSearch Service console UI, and the list of UI-supported first- and third-party integrations will continue to grow.

For any models not supported through the UI, you can instead set them up using the available APIs and the ML blueprints. For more information, refer to Introduction to OpenSearch Models. You can find blueprints for each connector in the ML Commons GitHub repository.

Prerequisites

Before connecting the model via the OpenSearch Service console, create an OpenSearch Service domain. Map an AWS Identity and Access Management (IAM) role by the name LambdaInvokeOpenSearchMLCommonsRole as the backend role on the ml_full_access role using the Security plugin on OpenSearch Dashboards, as shown in the following video. The OpenSearch Service integrations workflow is pre-filled to use the LambdaInvokeOpenSearchMLCommonsRole IAM role by default to create the connector between the OpenSearch Service domain and the model deployed on SageMaker. If you use a custom IAM role on the OpenSearch Service console integrations, make sure the custom role is mapped as the backend role with ml_full_access permissions prior to deploying the template.

Deploy the model using AWS CloudFormation

The following video demonstrates the steps to use the OpenSearch Service console to deploy a model within minutes on Amazon SageMaker and generate the model ID via the AI connectors. The first step is to choose Integrations in the navigation pane on the OpenSearch Service AWS console, which routes to a list of available integrations. The integration is set up through a UI, which will prompt you for the necessary inputs.

To set up the integration, you only need to provide the OpenSearch Service domain endpoint and provide a model name to uniquely identify the model connection. By default, the template deploys the Hugging Face sentence-transformers model, djl://ai.djl.huggingface.pytorch/sentence-transformers/all-MiniLM-L6-v2.

When you choose Create Stack, you are routed to the AWS CloudFormation console. The CloudFormation template deploys the architecture detailed in the following diagram.

The CloudFormation stack creates an AWS Lambda application that deploys a model from Amazon Simple Storage Service (Amazon S3), creates the connector, and generates the model ID in the output. You can then use this model ID to create a semantic index.

If the default all-MiniLM-L6-v2 model doesn’t serve your purpose, you can deploy any text embedding model of your choice on the chosen model host (SageMaker or Amazon Bedrock) by providing your model artifacts as an accessible S3 object. Alternatively, you can select one of the following pre-trained language models and deploy it to SageMaker. For instructions to set up your endpoint and models, refer to Available Amazon SageMaker Images.

SageMaker is a fully managed service that brings together a broad set of tools to enable high-performance, low-cost ML for any use case, delivering key benefits such as model monitoring, serverless hosting, and workflow automation for continuous training and deployment. SageMaker allows you to host and manage the lifecycle of text embedding models, and use them to power semantic search queries in OpenSearch Service. When connected, SageMaker hosts your models and OpenSearch Service is used to query based on inference results from SageMaker.

View the deployed model through OpenSearch Dashboards

To verify the CloudFormation template successfully deployed the model on the OpenSearch Service domain and get the model ID, you can use the ML Commons REST GET API through OpenSearch Dashboards Dev Tools.

The GET _plugins REST API now provides additional APIs to also view the model status. The following command allows you to see the status of a remote model:

GET _plugins/_ml/models/<modelid>

As shown in the following screenshot, a DEPLOYED status in the response indicates the model is successfully deployed on the OpenSearch Service cluster.

Alternatively, you can view the model deployed on your OpenSearch Service domain using the Machine Learning page of OpenSearch Dashboards.

This page lists the model information and the statuses of all the models deployed.

Create the neural pipeline using the model ID

When the status of the model shows as either DEPLOYED in Dev Tools or green and Responding in OpenSearch Dashboards, you can use the model ID to build your neural ingest pipeline. The following ingest pipeline is run in your domain’s OpenSearch Dashboards Dev Tools. Make sure you replace the model ID with the unique ID generated for the model deployed on your domain.

PUT _ingest/pipeline/neural-pipeline
{
  "description": "Semantic Search for retail product catalog ",
  "processors" : [
    {
      "text_embedding": {
        "model_id": "sfG4zosBIsICJFsINo3X",
        "field_map": {
           "description": "desc_v",
           "name": "name_v"
        }
      }
    }
  ]
}

Create the semantic search index using the neural pipeline as the default pipeline

You can now define your index mapping with the default pipeline configured to use the new neural pipeline you created in the previous step. Ensure the vector fields are declared as knn_vector and the dimensions are appropriate to the model that is deployed on SageMaker. If you have retained the default configuration to deploy the all-MiniLM-L6-v2 model on SageMaker, keep the following settings as is and run the command in Dev Tools.

PUT semantic_demostore
{
  "settings": {
    "index.knn": true,  
    "default_pipeline": "neural-pipeline",
    "number_of_shards": 1,
    "number_of_replicas": 1
  },
  "mappings": {
    "properties": {
      "desc_v": {
        "type": "knn_vector",
        "dimension": 384,
        "method": {
          "name": "hnsw",
          "engine": "nmslib",
          "space_type": "cosinesimil"
        }
      },
      "name_v": {
        "type": "knn_vector",
        "dimension": 384,
        "method": {
          "name": "hnsw",
          "engine": "nmslib",
          "space_type": "cosinesimil"
        }
      },
      "description": {
        "type": "text" 
      },
      "name": {
        "type": "text" 
      } 
    }
  }
}

Ingest sample documents to generate vectors

For this demo, you can ingest the sample retail demostore product catalog to the new semantic_demostore index. Replace the user name, password, and domain endpoint with your domain information and ingest raw data into OpenSearch Service:

curl -XPOST -u 'username:password' 'https://domain-end-point/_bulk' --data-binary @semantic_demostore.json -H 'Content-Type: application/json'

Validate the new semantic_demostore index

Now that you have ingested your dataset to the OpenSearch Service domain, validate if the required vectors are generated using a simple search to fetch all fields. Validate if the fields defined as knn_vectors have the required vectors.

Compare lexical search and semantic search powered by neural search using the Compare Search Results tool

The Compare Search Results tool on OpenSearch Dashboards is available for production workloads. You can navigate to the Compare search results page and compare query results between lexical search and neural search configured to use the model ID generated earlier.

Clean up

You can delete the resources you created following the instructions in this post by deleting the CloudFormation stack. This will delete the Lambda resources and the S3 bucket that contain the model that was deployed to SageMaker. Complete the following steps:

  1. On the AWS CloudFormation console, navigate to your stack details page.
  2. Choose Delete.

  1. Choose Delete to confirm.

You can monitor the stack deletion progress on the AWS CloudFormation console.

Note that, deleting the CloudFormation stack doesn’t delete the model deployed on the SageMaker domain and the AI/ML connector created. This is because these models and the connector can be associated with multiple indexes within the domain. To specifically delete a model and its associated connector, use the model APIs as shown in the following screenshots.

First, undeploy the model from the OpenSearch Service domain memory:

POST /_plugins/_ml/models/<model_id>/_undeploy

Then you can delete the model from the model index:

DELETE /_plugins/_ml/models/<model_id>

Lastly, delete the connector from the connector index:

DELETE /_plugins/_ml/connectors/<connector_id>

Conclusion

In this post, you learned how to deploy a model in SageMaker, create the AI/ML connector using the OpenSearch Service console, and build the neural search index. The ability to configure AI/ML connectors in OpenSearch Service simplifies the vector hydration process by making the integrations to external models native. You can create a neural search index in minutes using the neural ingestion pipeline and the neural search that use the model ID to generate the vector embedding on the fly during ingest and search.

To learn more about these AI/ML connectors, refer to Amazon OpenSearch Service AI connectors for AWS services, AWS CloudFormation template integrations for semantic search, and Creating connectors for third-party ML platforms.


About the Authors

Aruna Govindaraju is an Amazon OpenSearch Specialist Solutions Architect and has worked with many commercial and open source search engines. She is passionate about search, relevancy, and user experience. Her expertise with correlating end-user signals with search engine behavior has helped many customers improve their search experience.

Dagney Braun is a Principal Product Manager at AWS focused on OpenSearch.
Generate AI powered insights for Amazon Security Lake using Amazon SageMaker Studio and Amazon Bedrock

Post Syndicated from Jonathan Nguyen original https://aws.amazon.com/blogs/security/generate-ai-powered-insights-for-amazon-security-lake-using-amazon-sagemaker-studio-and-amazon-bedrock/

In part 1, we discussed how to use Amazon SageMaker Studio to analyze time-series data in Amazon Security Lake to identify critical areas and prioritize efforts to help increase your security posture. Security Lake provides additional visibility into your environment by consolidating and normalizing security data from both AWS and non-AWS sources. Security teams can use Amazon Athena to query data in Security Lake to aid in a security event investigation or proactive threat analysis. Reducing the security team’s mean time to respond to or detect a security event can decrease your organization’s security vulnerabilities and risks, minimize data breaches, and reduce operational disruptions. Even if your security team is already familiar with AWS security logs and is using SQL queries to sift through data, determining appropriate log sources to review and crafting customized SQL queries can add time to an investigation. Furthermore, when security analysts conduct their analysis using SQL queries, the results are point-in-time and don’t automatically factor results from previous queries.

In this blog post, we show you how to extend the capabilities of SageMaker Studio by using Amazon Bedrock, a fully-managed generative artificial intelligence (AI) service natively offering high-performing foundation models (FMs) from leading AI companies with a single API. By using Amazon Bedrock, security analysts can accelerate security investigations by using a natural language companion to automatically generate SQL queries, focus on relevant data sources within Security Lake, and use previous SQL query results to enhance the results from future queries. We walk through a threat analysis exercise to show how your security analysts can use natural language processing to answer questions such as which AWS account has the most AWS Security Hub findings, irregular network activity from AWS resources, or which AWS Identity and Access Management (IAM) principals invoked highly suspicious activity. By identifying possible vulnerabilities or misconfigurations, you can minimize mean time to detect and pinpoint specific resources to assess overall impact. We also discuss methods to customize Amazon Bedrock integration with data from your Security Lake. While large language models (LLMs) are useful conversational partners, it’s important to note that LLM responses can include hallucinations, which might not reflect truth or reality. We discuss some mechanisms to validate LLM responses and mitigate hallucinations. This blog post is best suited for technologists who have an in-depth understanding of generative artificial intelligence concepts and the AWS services used in the example solution.

Solution overview

Figure 1 depicts the architecture of the sample solution.

Figure 1: Security Lake generative AI solution architecture

Figure 1: Security Lake generative AI solution architecture

Before you deploy the sample solution, complete the following prerequisites:

  1. Enable Security Lake in your organization in AWS Organizations and specify a delegated administrator account to manage the Security Lake configuration for all member accounts in your organization. Configure Security Lake with the appropriate log sources: Amazon Virtual Private Cloud (VPC) Flow Logs, AWS Security Hub, AWS CloudTrail, and Amazon Route53.
  2. Create subscriber query access from the source Security Lake AWS account to the subscriber AWS account.
  3. Accept a resource share request in the subscriber AWS account in AWS Resource Access Manager (AWS RAM).
  4. Create a database link in AWS Lake Formation in the subscriber AWS account and grant access for the Athena tables in the Security Lake AWS account.
  5. Grant Claude v2 model access for Amazon Bedrock LLM Claude v2 in the AWS subscriber account where you will deploy the solution. If you try to use a model before you enable it in your AWS account, you will get an error message.

After you set up the prerequisites, the sample solution architecture provisions the following resources:

  1. A VPC is provisioned for SageMaker with an internet gateway, a NAT gateway, and VPC endpoints for all AWS services within the solution. An internet gateway or NAT gateway is required to install external open-source packages.
  2. A SageMaker Studio domain is created in VPCOnly mode with a single SageMaker user-profile that’s tied to an IAM role. As part of the SageMaker deployment, an Amazon Elastic File System (Amazon EFS) is provisioned for the SageMaker domain.
  3. A dedicated IAM role is created to restrict access to create or access the SageMaker domain’s presigned URL from a specific Classless Inter-Domain Routing (CIDR) for accessing the SageMaker notebook.
  4. An AWS CodeCommit repository containing Python notebooks used for the artificial intelligence and machine learning (AI/ML) workflow by the SageMaker user profile.
  5. An Athena workgroup is created for Security Lake queries with a S3 bucket for output location (access logging is configured for the output bucket).

Cost

Before deploying the sample solution and walking through this post, it’s important to understand the cost factors for the main AWS services being used. The cost will largely depend on the amount of data you interact with in Security Lake and the duration of running resources in SageMaker Studio.

  1. A SageMaker Studio domain is deployed and configured with default setting of a ml.t3.medium instance type. For a more detailed breakdown, see SageMaker Studio pricing. It’s important to shut down applications when they’re not in use because you’re billed for the number of hours an application is running. See the AWS samples repository for an automated shutdown extension.
  2. Amazon Bedrock on-demand pricing is based on the selected LLM and the number of input and output tokens. A token is comprised of a few characters and refers to the basic unit of text that a model learns to understand the user input and prompts. For a more detailed breakdown, see Amazon Bedrock pricing.
  3. The SQL queries generated by Amazon Bedrock are invoked using Athena. Athena cost is based on the amount of data scanned within Security Lake for that query. For a more detailed breakdown, see Athena pricing.

Deploy the sample solution

You can deploy the sample solution by using either the AWS Management Console or the AWS Cloud Development Kit (AWS CDK). For instructions and more information on using the AWS CDK, see Get Started with AWS CDK.

Option 1: Deploy using AWS CloudFormation using the console

Use the console to sign in to your subscriber AWS account and then choose the Launch Stack button to open the AWS CloudFormation console that’s pre-loaded with the template for this solution. It takes approximately 10 minutes for the CloudFormation stack to complete.

Select the Launch Stack button to launch the template

Option 2: Deploy using AWS CDK

  1. Clone the Security Lake generative AI sample repository.
  2. Navigate to the project’s source folder (…/amazon-security-lake-generative-ai/source).
  3. Install project dependencies using the following commands:
    npm install -g aws-cdk-lib
    npm install
    

  4. On deployment, you must provide the following required parameters:
    • IAMroleassumptionforsagemakerpresignedurl – this is the existing IAM role you want to use to access the AWS console to create presigned URLs for SageMaker Studio domain.
    • securitylakeawsaccount – this is the AWS account ID where Security Lake is deployed.
  5. Run the following commands in your terminal while signed in to your subscriber AWS account. Replace <INSERT_AWS_ACCOUNT> with your account number and replace <INSERT_REGION> with the AWS Region that you want the solution deployed to.
    cdk bootstrap aws://<INSERT_AWS_ACCOUNT>/<INSERT_REGION>
    
    cdk deploy --parameters IAMroleassumptionforsagemakerpresignedurl=arn:aws:iam::<INSERT_AWS_ACCOUNT>:role/<INSERT_IAM_ROLE_NAME> --parameters securitylakeawsaccount=<INSERT_SECURITY_LAKE_AWS_ACCOUNT_ID>
    

Post-deployment configuration steps

Now that you’ve deployed the solution, you must add permissions to allow SageMaker and Amazon Bedrock to interact with your Security Lake data.

Grant permission to the Security Lake database

  1. Copy the SageMaker user profile Amazon Resource Name (ARN)
    arn:aws:iam::<account-id>:role/sagemaker-user-profile-for-security-lake
    

  2. Go to the Lake Formation console.
  3. Select the amazon_security_lake_glue_db_<YOUR-REGION> database. For example, if your Security Lake is in us-east-1, the value would be amazon_security_lake_glue_db_us_east_1
  4. For Actions, select Grant.
  5. In Grant Data Permissions, select SAML Users and Groups.
  6. Paste the SageMaker user profile ARN from Step 1.
  7. In Database Permissions, select Describe, and then Grant.

Grant permission to Security Lake tables

You must repeat these steps for each source configured within Security Lake. For example, if you have four sources configured within Security Lake, you must grant permissions for the SageMaker user profile to four tables. If you have multiple sources that are in separate Regions and you don’t have a rollup Region configured in Security Lake, you must repeat the steps for each source in each Region.

The following example grants permissions to the Security Hub table within Security Lake. For more information about granting table permissions, see the AWS LakeFormation user-guide.

  1. Copy the SageMaker user-profile ARN arn:aws:iam:<account-id>:role/sagemaker-user-profile-for-security-lake.
  2. Go to the Lake Formation console.
  3. Select the amazon_security_lake_glue_db_<YOUR-REGION> database.
    For example, if your Security Lake database is in us-east-1 the value would be amazon_security_lake_glue_db_us_east_1
  4. Choose View Tables.
  5. Select the amazon_security_lake_table_<YOUR-REGION>_sh_findings_1_0 table.
    For example, if your Security Lake table is in us-east-1 the value would be amazon_security_lake_table_us_east_1_sh_findings_1_0

    Note: Each table must be granted access individually. Selecting All Tables won’t grant the access needed to query Security Lake.

  6. For Actions, select Grant.
  7. In Grant Data Permissions, select SAML Users and Groups.
  8. Paste the SageMaker user profile ARN from Step 1.
  9. In Table Permissions, select Describe, and then Grant.

Launch your SageMaker Studio application

Now that you’ve granted permissions for a SageMaker user profile, you can move on to launching the SageMaker application associated to that user profile.

  1. Navigate to the SageMaker Studio domain in the console.
  2. Select the SageMaker domain security-lake-gen-ai-<subscriber-account-id>.
  3. Select the SageMaker user profile sagemaker-user-profile-for-security-lake.
  4. For Launch, select Studio.
Figure 2: SageMaker Studio domain view

Figure 2: SageMaker Studio domain view

Clone the Python notebook

As part of the solution deployment, we’ve created a foundational Python notebook in CodeCommit to use within your SageMaker app.

  1. Navigate to CloudFormation in the console.
  2. In the Stacks section, select the SageMakerDomainStack.
  3. Select the Outputs tab.
  4. Copy the value for the SageMaker notebook generative AI repository URL. (For example: https://git-codecommit.us-east-1.amazonaws.com/v1/repos/sagemaker_gen_ai_repo)
  5. Go back to your SageMaker app.
  6. In SageMaker Studio, in the left sidebar, choose the Git icon (a diamond with two branches), then choose Clone a Repository.
    Figure 3: SageMaker Studio clone repository option

    Figure 3: SageMaker Studio clone repository option

  7. Paste the CodeCommit repository link from Step 4 under the Git repository URL (git). After you paste the URL, select Clone “https://git-codecommit.us-east-1.amazonaws.com/v1/repos/sagemaker_gen_ai_repo”, then select Clone.

Note: If you don’t select from the auto-populated list, SageMaker won’t be able to clone the repository and will return a message that the URL is invalid.

Figure 4: SageMaker Studio clone HTTPS repository URL

Figure 4: SageMaker Studio clone HTTPS repository URL

Configure your notebook to use generative AI

In the next section, we walk through how we configured the notebook and why we used specific LLMs, agents, tools, and additional configurations so you can extend and customize this solution to your use case.

The notebook we created uses the LangChain framework. LangChain is a framework for developing applications powered by language models and processes natural language inputs from the user, generates SQL queries, and runs those queries on your Security Lake data. For our use case, we’re using LangChain with Anthropic’s Claude 2 model on Amazon Bedrock.

Set up the notebook environment

  1. After you’re in the generative_ai_security_lake.ipynb notebook, you can set up your notebook environment. Keep the default settings and choose Select.
    Figure 5: SageMaker Studio notebook start-up configuration

    Figure 5: SageMaker Studio notebook start-up configuration

  2. Run the first cell to install the requirements listed in the requirements.txt file.

Connect to the Security Lake database using SQLAlchemy

The example solution uses a pre-populated Security Lake database with metadata in the AWS Glue Data Catalog. The inferred schema enables the LLM to generate SQL queries in response to the questions being asked.

LangChain uses SQLAlchemy, which is a Python SQL toolkit and object relational mapper, to access databases. To connect to a database, first import SQLAlchemy and create an engine object by specifying the following:

  • SCHEMA_NAME
  • S3_STAGING_DIR
  • AWS_REGION
  • ATHENA REST API details

You can use the following configuration code to establish database connections and start querying.

import os
ACCOUNT_ID = os.environ["AWS_ACCOUNT_ID"]
REGION_NAME = os.environ.get('REGION_NAME', 'us-east-1')
REGION_FMT = REGION_NAME.replace("-","_")

from langchain import SQLDatabase
from sqlalchemy import create_engine

#Amazon Security Lake Database
SCHEMA_NAME = f"amazon_security_lake_glue_db_{REGION_FMT}"

#S3 Staging location for Athena query output results and this will be created by deploying the Cloud Formation stack
S3_STAGING_DIR = f's3://athena-gen-ai-bucket-results-{ACCOUNT_ID}/output/'

engine_athena = create_engine(
    "awsathena+rest://@athena.{}.amazonaws.com:443/{}?s3_staging_dir={}".
    format(REGION_NAME, SCHEMA_NAME, S3_STAGING_DIR)
)

athena_db = SQLDatabase(engine_athena)
db = athena_db

Initialize the LLM and Amazon Bedrock endpoint URL

Amazon Bedrock provides a list of Region-specific endpoints for making inference requests for models hosted in Amazon Bedrock. In this post, we’ve defined the model ID as Claude v2 and the Amazon Bedrock endpoint as us-east-1. You can change this to other LLMs and endpoints as needed for your use case.

Obtain a model ID from the AWS console

  1. Go to the Amazon Bedrock console.
  2. In the navigation pane, under Foundation models, select Providers.
  3. Select the Anthropic tab from the top menu and then select Claude v2.
  4. In the model API request note the model ID value in the JSON payload.

Note: Alternatively, you can use the AWS Command Line Interface (AWS CLI) to run the list-foundation-models command in a SageMaker notebook cell or a CLI terminal to the get the model ID. For AWS SDK, you can use the ListFoundationModels operation to retrieve information about base models for a specific provider.

Figure 6: Amazon Bedrock Claude v2 model ID

Figure 6: Amazon Bedrock Claude v2 model ID

Set the model parameters

After the LLM and Amazon Bedrock endpoints are configured, you can use the model_kwargs dictionary to set model parameters. Depending on your use case, you might use different parameters or values. In this example, the following values are already configured in the notebook and passed to the model.

  1. temperature: Set to 0. Temperature controls the degree of randomness in responses from the LLM. By adjusting the temperature, users can control the balance between having predictable, consistent responses (value closer to 0) compared to more creative, novel responses (value closer to 1).

    Note: Instead of using the temperature parameter, you can set top_p, which defines a cutoff based on the sum of probabilities of the potential choices. If you set Top P below 1.0, the model considers the most probable options and ignores less probable ones. According to Anthropic’s user guide, “you should either alter temperature or top_p, but not both.”

  2. top_k: Set to 0. While temperature controls the probability distribution of potential tokens, top_k limits the sample size for each subsequent token. For example, if top_k=50, the model selects from the 50 most probable tokens that could be next in a sequence. When you lower the top_k value, you remove the long tail of low probability tokens to select from in a sequence.
  3. max_tokens_to_sample: Set to 4096. For Anthropic models, the default is 256 and the max is 4096. This value denotes the absolute maximum number of tokens to predict before the generation stops. Anthropic models can stop before reaching this maximum.
Figure 7: Notebook configuration for Amazon Bedrock

Figure 7: Notebook configuration for Amazon Bedrock

Create and configure the LangChain agent

An agent uses a LLM and tools to reason and determine what actions to take and in which order. For this use case, we used a Conversational ReAct agent to remember conversational history and results to be used in a ReAct loop (Question → Thought → Action → Action Input → Observation ↔ repeat → Answer). This way, you don’t have to remember how to incorporate previous results in the subsequent question or query. Depending on your use case, you can configure a different type of agent.

Create a list of tools

Tools are functions used by an agent to interact with the available dataset. The agent’s tools are used by an action agent. We import both SQL and Python REPL tools:

  1. List the available log source tables in the Security Lake database
  2. Extract the schema and sample rows from the log source tables
  3. Create SQL queries to invoke in Athena
  4. Validate and rewrite the queries in case of syntax errors
  5. Invoke the query to get results from the appropriate log source tables
Figure 8: Notebook LangChain agent tools

Figure 8: Notebook LangChain agent tools

Here’s a breakdown for the tools used and the respective prompts:

  • QuerySQLDataBaseTool: This tool accepts detailed and correct SQL queries as input and returns results from the database. If the query is incorrect, you receive an error message. If there’s an error, rewrite and recheck the query, and try again. If you encounter an error such as Unknown column xxxx in field list, use the sql_db_schema to verify the correct table fields.
  • InfoSQLDatabaseTool: This tool accepts a comma-separated list of tables as input and returns the schema and sample rows for those tables. Verify that the tables exist by invoking the sql_db_list_tables first. The input format is: table1, table2, table3
  • ListSQLDatabaseTool: The input is an empty string, the output is a comma separated list of tables in the database
  • QuerySQLCheckerTool: Use this tool to check if your query is correct before running it. Always use this tool before running a query with sql_db_query
  • PythonREPLTool: A Python shell. Use this to run python commands. The input should be a valid python command. If you want to see the output of a value, you should print it out with print(…).

Note: If a native tool doesn’t meet your needs, you can create custom tools. Throughout our testing, we found some of the native tools provided most of what we needed but required minor tweaks for our use case. We changed the default behavior for the tools for use with Security Lake data.

Create an output parser

Output parsers are used to instruct the LLM to respond in the desired output format. Although the output parser is optional, it makes sure the LLM response is formatted in a way that can be quickly consumed and is actionable by the user.

Figure 9: LangChain output parser setting

Figure 9: LangChain output parser setting

Adding conversation buffer memory

To make things simpler for the user, previous results should be stored for use in subsequent queries by the Conversational ReAct agent. ConversationBufferMemory provides the capability to maintain state from past conversations and enables the user to ask follow-up questions in the same chat context. For example, if you asked an agent for a list of AWS accounts to focus on, you want your subsequent questions to focus on that same list of AWS accounts instead of writing the values down somewhere and keeping track of it in the next set of questions. There are many other types of memory that can be used to optimize your use cases.

Figure 10: LangChain conversation buffer memory setting

Figure 10: LangChain conversation buffer memory setting

Initialize the agent

At this point, all the appropriate configurations are set and it’s time to load an agent executor by providing a set of tools and a LLM.

  1. tools: List of tools the agent will have access to.
  2. llm: LLM the agent will use.
  3. agent: Agent type to use. If there is no value provided and agent_path is set, the agent used will default to AgentType.ZERO_SHOT_REACT_DESCRIPTION.
  4. agent_kwargs: Additional keyword arguments to pass to the agent.
Figure 11: LangChain agent initialization

Figure 11: LangChain agent initialization

Note: For this post, we set verbose=True to view the agent’s intermediate ReAct steps, while answering questions. If you’re only interested in the output, set verbose=False.

You can also set return_direct=True to have the tool output returned to the user and closing the agent loop. Since we want to maintain the results of the query and used by the LLM, we left the default value of return_direct=False.

Provide instructions to the agent on using the tools

In addition to providing the agent with a list of tools, you would also give instructions to the agent on how and when to use these tools for your use case. This is optional but provides the agent with more context and can lead to better results.

Figure 12: LangChain agent instructions

Figure 12: LangChain agent instructions

Start your threat analysis journey with the generative AI-powered agent

Now that you’ve walked through the same set up process we used to create and initialize the agent, we can demonstrate how to analyze Security Lake data using natural language input questions that a security researcher might ask. The following examples focus on how you can use the solution to identify security vulnerabilities, risks, and threats and prioritize mitigating them. For this post, we’re using native AWS sources, but the agent can analyze any custom log sources configured in Security Lake. You can also use this solution to assist with investigations of possible security events in your environment.

For each of the questions that follow, you would enter the question in the free-form cell after it has run, similar to Figure 13.

Note: Because the field is free form, you can change the questions. Depending on the changes, you might see different results than are shown in this post. To end the conversation, enter exit and press the Enter key.

Figure 13: LangChain agent conversation input

Figure 13: LangChain agent conversation input

Question 1: What data sources are available in Security Lake?

In addition to the native AWS sources that Security Lake automatically ingests, your security team can incorporate additional custom log sources. It’s important to know what data is available to you to determine what and where to investigate. As shown in Figure 14, the Security Lake database contains the following log sources as tables:

If there are additional custom sources configured, they will also show up here. From here, you can focus on a smaller subset of AWS accounts that might have a larger number of security-related findings.

Figure 14: LangChain agent output for Security Lake tables

Figure 14: LangChain agent output for Security Lake tables

Question 2: What are the top five AWS accounts that have the most Security Hub findings?

Security Hub is a cloud security posture management service that not only aggregates findings from other AWS security services—such as Amazon GuardDuty, Amazon Macie, AWS Firewall Manager, and Amazon Inspector—but also from a number of AWS partner security solutions. Additionally, Security Hub has its own security best practices checks to help identify any vulnerabilities within your AWS environment. Depending on your environment, this might be a good starting place to look for specific AWS accounts to focus on.

Figure 15: LangChain output for AWS accounts with Security Hub findings

Figure 15: LangChain output for AWS accounts with Security Hub findings

Question 3: Within those AWS accounts, were any of the following actions found in (CreateUser, AttachUserPolicy, CreateAccessKey, CreateLoginProfile, DeleteTrail, DeleteMembers, UpdateIPSet, AuthorizeSecurityGroupIngress) in CloudTrail?

With the list of AWS accounts to look at narrowed down, you might be interested in mutable changes in your AWS account that you would deem suspicious. It’s important to note that every AWS environment is different, and some actions might be suspicious for one environment but normal in another. You can tailor this list to actions that shouldn’t happen in your environment. For example, if your organization normally doesn’t use IAM users, you can change the list to look at a list of actions for IAM, such as CreateAccessKey, CreateLoginProfile, CreateUser, UpdateAccessKey, UpdateLoginProfile, and UpdateUser.

By looking at the actions related to AWS CloudTrail (CreateUser, AttachUserPolicy, CreateAccessKey, CreateLoginProfile, DeleteTrail, DeleteMembers, UpdateIPSet, AuthorizeSecurityGroupIngress), you can see which actions were taken in your environment and choose which to focus on. Because the agent has access to previous chat history and results, you can ask follow-up questions on the SQL results without having to specify the AWS account IDs or event names.

Figure 16: LangChain agent output for CloudTrail actions taken in AWS Organization

Figure 16: LangChain agent output for CloudTrail actions taken in AWS Organization

Question 4: Which IAM principals took those actions?

The previous question narrowed down the list to mutable actions that shouldn’t occur. The next logical step is to determine which IAM principals took those actions. This helps correlate an actor to the actions that are either unexpected or are reserved for only authorized principals. For example, if you have an IAM principal tied to a continuous integration and delivery (CI/CD) pipeline, that could be less suspicious. Alternatively, if you see an IAM principal that you don’t recognize, you could focus on all actions taken by that IAM principal, including how it was provisioned in the first place.

Figure 17: LangChain agent output for CloudTrail IAM principals that invoked events from the previous query

Figure 17: LangChain agent output for CloudTrail IAM principals that invoked events from the previous query

Question 5: Within those AWS accounts, were there any connections made to “3.0.0.0/8”?

If you don’t find anything useful related to mutable changes to CloudTrail, you can pivot to see if there were any network connections established from a specific Classless Inter-Domain Routing (CIDR) range. For example, if an organization primarily interacts with AWS resources within your AWS Organizations from your corporate-owned CIDR range, anything outside of that might be suspicious. Additionally, if you have threat lists or suspicious IP ranges, you can add them to the query to see if there are any network connections established from those ranges. The agent knows that the query is network related and to look in VPC flow logs and is focusing on only the AWS accounts from Question 2.

Figure 18: LangChain agent output for VPC flow log matches to specific CIDR

Figure 18: LangChain agent output for VPC flow log matches to specific CIDR

Question 6: As a security analyst, what other evidence or logs should I look for to determine if there are any indicators of compromise in my AWS environment?

If you haven’t found what you’re looking for and want some inspiration from the agent, you can ask the agent what other areas you should look at within your AWS environment. This might help you create a threat analysis thesis or use case as a starting point. You can also refer to the MITRE ATT&CK Cloud Matrix for more areas to focus on when setting up questions for your agent.

Figure 19: LangChain agent output for additional scenarios and questions to investigate

Figure 19: LangChain agent output for additional scenarios and questions to investigate

Based on the answers given, you can start a new investigation to identify possible vulnerabilities and threats:

  • Is there any unusual API activity in my organization that could be an indicator of compromise?
  • Have there been any AWS console logins that don’t match normal geographic patterns?
  • Have there been any spikes in network traffic for my AWS resources?

Agent running custom SQL queries

If you want to use a previously generated or customized SQL query, the agent can run the query as shown in Figure 20 that follows. In the previous questions, a SQL query is generated in the agent’s Action Input field. You can use that SQL query as a baseline, edit the SQL query manually to fit your use case, and then run the modified query through the agent. The modified query results are stored in memory and can be used for subsequent natural language questions to the agent. Even if your security analysts already have SQL experience, having the agent give a recommendation or template SQL query can shorten your investigation.

Figure 20: LangChain agent output for invoking custom SQL queries

Figure 20: LangChain agent output for invoking custom SQL queries

Agent assistance to automatically generate visualizations

You can get help from the agent to create visualizations by using the PythonREPL tool to generate code and plot SQL query results. As shown in Figure 21, you can ask the agent to get results from a SQL query and generate code to create a visualization based on those results. You can then take the generated code and put it into the next cell to create the visualization.

Figure 21: LangChain agent output to generate code to visualize SQL results in a plot

Figure 21: LangChain agent output to generate code to visualize SQL results in a plot

The agent returns example code after To plot the results. You can copy the code between ‘‘‘python and ’’’ and input that code in the next cell. After you run that cell, a visual based on the SQL results is created similar to Figure 22 that follows. This can be helpful to share the notebook output as part of an investigation to either create a custom detection to monitor or determine how a vulnerability can be mitigated.

Figure 22: Notebook Python code output from code generated by LangChain agent

Figure 22: Notebook Python code output from code generated by LangChain agent

Tailoring your agent to your data

As previously discussed, use cases and data vary between organizations. It’s important to understand the foundational components in terms of how you can configure and tailor the LLM, agents, tools, and configuration to your environment. The notebook in the solution was the result of experiments to determine and display what’s possible. Along the way, you might encounter challenges or issues depending on changes you make in the notebook or by adding additional data sources. Below are some tips to help you create and tailor the notebook to your use case.

  • If the agent pauses in the intermediate steps or asks for guidance to answer the original question, you can guide the agent with prompt engineering techniques, using commands such as execute or continue to move the process along.
  • If the agent is hallucinating or providing data that isn’t accurate, see Anthropic’s user guide for mechanisms to reduce hallucinations. An example of a hallucination would be the response having generic information such as an AWS account that is 1234567890 or the resulting count of a query being repeated for multiple rows.

    Note: You can also use Retrieval Augmented Generation (RAG) in Amazon SageMaker to mitigate hallucinations.

SageMaker Studio and Amazon Bedrock provide native integration to use a variety of generative AI tools with your Security Lake data to help increase your organization’s security posture. Some other use cases you can try include:

  • Investigating impact and root cause for a suspected compromise of an Amazon Elastic Compute Cloud (Amazon EC2) instance from a GuardDuty finding.
  • Determining if network ACL or firewall changes in your environment affected the number of AWS resources communicating with public endpoints.
  • Checking if any S3 buckets with possibly confidential or sensitive data were accessed by non-authorized IAM principals.
  • Identify if an EC2 instance that might be compromised made any internal or external connections to other AWS resources and then if those resources were impacted.

Conclusion

This solution demonstrates how you can use the generative AI capabilities of Amazon Bedrock and natural language input in SageMaker Studio to analyze data in Security Lake and work towards reducing your organization’s risk and increase your security posture. The Python notebook is primarily meant to serve as a starting point to walk through an example scenario to identify potential vulnerabilities and threats.

Security Lake is continually working on integrating native AWS sources, but there are also custom data sources outside of AWS that you might want to import for your agent to analyze. We also showed you how we configured the notebook to use agents and LLMs, and how you can tune each component within a notebook to your specific use case.

By enabling your security team to analyze and interact with data in Security Lake using natural language input, you can reduce the amount of time needed to conduct an investigation by automatically identifying the appropriate data sources, generating and invoking SQL queries, and visualizing data from your investigation. This post focuses on Security Lake, which normalizes data into Open Cybersecurity Schema Framework (OCSF), but as long as the database data schema is normalized, the solution can be applied to other data stores.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the Generative AI on AWS re:Post or contact AWS Support.

Author

Jonathan Nguyen

Jonathan is a Principal Security Architect at AWS. His background is in AWS security with a focus on threat detection and incident response. He helps enterprise customers develop a comprehensive AWS security strategy and deploy security solutions at scale, and trains customers on AWS security best practices.

Madhunika-Reddy-Mikkili

Madhunika Reddy Mikkili

Madhunika is a Data and Machine Learning Engineer with the AWS Professional Services Shared Delivery Team. She is passionate about helping customers achieve their goals through the use of data and machine learning insights. Outside of work, she loves traveling and spending time with family and friends.

Harsh Asnani

Harsh Asnani

Harsh is a Machine Learning Engineer at AWS. His Background is in applied Data Science with a focus on operationalizing Machine Learning workloads in the cloud at scale.

Kartik Kannapur

Kartik Kannapur

Kartik is a Senior Data Scientist with AWS Professional Services. His background is in Applied Mathematics and Statistics. He works with enterprise customers, helping them use machine learning to solve their business problems.

Disaster recovery strategies for Amazon MWAA – Part 1

Post Syndicated from Parnab Basak original https://aws.amazon.com/blogs/big-data/disaster-recovery-strategies-for-amazon-mwaa-part-1/

In the dynamic world of cloud computing, ensuring the resilience and availability of critical applications is paramount. Disaster recovery (DR) is the process by which an organization anticipates and addresses technology-related disasters. For organizations implementing critical workload orchestration using Amazon Managed Workflows for Apache Airflow (Amazon MWAA), it is crucial to have a DR plan in place to ensure business continuity.

In this series, we explore the need for Amazon MWAA disaster recovery and prescribe solutions that will sustain Amazon MWAA environments against unintended disruptions. This lets you to define, avoid, and handle disruption risks as part of your business continuity plan. This post focuses on designing the overall DR architecture. A future post in this series will focus on implementing the individual components using AWS services.

The need for Amazon MWAA disaster recovery

Amazon MWAA, a fully managed service for Apache Airflow, brings immense value to organizations by automating workflow orchestration for extract, transform, and load (ETL), DevOps, and machine learning (ML) workloads. Amazon MWAA has a distributed architecture with multiple components such as scheduler, worker, web server, queue, and database. This makes it difficult to implement a comprehensive DR strategy.

An active Amazon MWAA environment continuously parses Airflow Directed Acyclic Graphs (DAGs), reading them from a configured Amazon Simple Storage Service (Amazon S3) bucket. DAG source unavailability due to network unreachability, unintended corruption, or deletes leads to extended downtime and service disruption.

Within Airflow, the metadata database is a core component storing configuration variables, roles, permissions, and DAG run histories. A healthy metadata database is therefore critical for your Airflow environment. As with any core Airflow component, having a backup and disaster recovery plan in place for the metadata database is essential.

Amazon MWAA deploys Airflow components to multiple Availability Zones within your VPC in your preferred AWS Region. This provides fault tolerance and automatic recovery against a single Availability Zone failure. For mission-critical workloads, being resilient to the impairments of a unitary Region through multi-Region deployments is additionally important to ensure high availability and business continuity.

Balancing between costs to maintain redundant infrastructures, complexity, and recovery time is essential for Amazon MWAA environments. Organizations aim for cost-effective solutions that minimize their Recovery Time Objective (RTO) and Recovery Point Objective (RPO) to meet their service level agreements, be economically viable, and meet their customers’ demands.

Detect disasters in the primary environment: Proactive monitoring through metrics and alarms

Prompt detection of disasters in the primary environment is crucial for timely disaster recovery. Monitoring the Amazon CloudWatch SchedulerHeartbeat metric provides insights into Airflow health of an active Amazon MWAA environment. You can add other health check metrics to the evaluation criteria, such as checking the availability of upstream or downstream systems and network reachability. Combined with CloudWatch alarms, you can send notifications when these thresholds over a number of time periods are not met. You can add alarms to dashboards to monitor and receive alerts about your AWS resources and applications across multiple Regions.

AWS publishes our most up-to-the-minute information on service availability on the Service Health Dashboard. You can check at any time to get current status information, or subscribe to an RSS feed to be notified of interruptions to each individual service in your operating Region. The AWS Health Dashboard provides information about AWS Health events that can affect your account.

By combining metric monitoring, available dashboards, and automatic alarming, you can promptly detect unavailability of your primary environment, enabling proactive measures to transition to your DR plan. It is critical to factor in incident detection, notification, escalation, discovery, and declaration into your DR planning and implementation to provide realistic and achievable objectives that provide business value.

In the following sections, we discuss two Amazon MWAA DR strategy solutions and their architecture.

DR strategy solution 1: Backup and restore

The backup and restore strategy involves generating Airflow component backups in the same or different Region as your primary Amazon MWAA environment. To ensure continuity, you can asynchronously replicate these to your DR Region, with minimal performance impact on your primary Amazon MWAA environment. In the event of a rare primary Regional impairment or service disruption, this strategy will create a new Amazon MWAA environment and recover historical data to it from existing backups. However, it’s important to note that during the recovery process, there will be a period where no Airflow environments are operational to process workflows until the new environment is fully provisioned and marked as available.

This strategy provides a low-cost and low-complexity solution that is also suitable for mitigating against data loss or corruption within your primary Region. The amount of data being backed up and the time to create a new Amazon MWAA environment (typically 20–30 minutes) affects how quickly restoration can happen. To enable infrastructure to be redeployed quickly without errors, deploy using infrastructure as code (IaC). Without IaC, it may be complex to restore an analogous DR environment, which will lead to increased recovery times and possibly exceed your RTO.

Let’s explore the setup required when your primary Amazon MWAA environment is actively running, as shown in the following figure.

Backup and Restore - Pre

The solution comprises three key components. The first component is the primary environment, where the Airflow workflows are initially deployed and actively running. The second component is the disaster monitoring component, comprised of CloudWatch and a combination of an AWS Step Functions state machine and a AWS Lambda function. The third component is for creating and storing backups of all configurations and metadata that is required to restore. This can be in the same Region as your primary or replicated to your DR Region using S3 Cross-Region Replication (CRR). For CRR, you also pay for inter-Region data transfer out from Amazon S3 to each destination Region.

The first three steps in the workflow are as follows:

  1. As part of your backup creation process, Airflow metadata is replicated to an S3 bucket using an export DAG utility, run periodically based on your RPO interval.
  2. Your existing primary Amazon MWAA environment automatically emits the status of its scheduler’s health to the CloudWatch SchedulerHeartbeat metric.
  3. A multi-step Step Functions state machine is triggered from a periodic Amazon EventBridge schedule to monitor the scheduler’s health status. As the primary step of the state machine, a Lambda function evaluates the status of the SchedulerHeartbeat metric. If the metric is deemed healthy, no action is taken.

The following figure illustrates the additional steps in the solution workflow.

Backup and Restore post

  1. When the heartbeat count deviates from the normal count for a period of time, a series of actions are initiated to recover to a new Amazon MWAA environment in the DR Region. These actions include starting creation of a new Amazon MWAA environment, replicating the primary environment configurations, and then waiting for the new environment to become available.
  2. When the environment is available, an import DAG utility is run to restore the metadata contents from the backups. Any DAG runs that were interrupted during the impairment of the primary environment need to be manually rerun to maintain service level agreements. Future DAG runs are queued to run as per their next configured schedule.

DR strategy solution 2: Active-passive environments with periodic data synchronization

The active-passive environments with periodic data synchronization strategy focuses on maintaining recurrent data synchronization between an active primary and a passive Amazon MWAA DR environment. By periodically updating and synchronizing DAG stores and metadata databases, this strategy ensures that the DR environment remains current or nearly current with the primary. The DR Region can be the same or a different Region than your primary Amazon MWAA environment. In the event of a disaster, backups are available to revert to a previous known good state to minimize data loss or corruption.

This strategy provides low RTO and RPO with frequent synchronization, allowing quick recovery with minimal data loss. The infrastructure costs and code deployments are compounded to maintain both the primary and DR Amazon MWAA environments. Your DR environment is available immediately to run DAGs on.

The following figure illustrates the setup required when your primary Amazon MWAA environment is actively running.

Active Passive pre

The solution comprises four key components. Similar to the backup and restore solution, the first component is the primary environment, where the workflow is initially deployed and is actively running. The second component is the disaster monitoring component, consisting of CloudWatch and a combination of a Step Functions state machine and Lambda function. The third component creates and stores backups for all configurations and metadata required for the database synchronization. This can be in the same Region as your primary or replicated to your DR Region using Amazon S3 Cross-Region Replication. As mentioned earlier, for CRR, you also pay for inter-Region data transfer out from Amazon S3 to each destination Region. The last component is a passive Amazon MWAA environment that has the same Airflow code and environment configurations as the primary. The DAGs are deployed in the DR environment using the same continuous integration and continuous delivery (CI/CD) pipeline as the primary. Unlike the primary, DAGs are kept in a paused state to not cause duplicate runs.

The first steps of the workflow are similar to the backup and restore strategy:

  1. As part of your backup creation process, Airflow metadata is replicated to an S3 bucket using an export DAG utility, run periodically based on your RPO interval.
  2. Your existing primary Amazon MWAA environment automatically emits the status of its scheduler’s health to CloudWatch SchedulerHeartbeat metric.
  3. A multi-step Step Functions state machine is triggered from a periodic Amazon EventBridge schedule to monitor scheduler health status. As the primary step of the state machine, a Lambda function evaluates the status of the SchedulerHeartbeat metric. If the metric is deemed healthy, no action is taken.

The following figure illustrates the final steps of the workflow.

Active Passive post

  1. When the heartbeat count deviates from the normal count for a period of time, DR actions are initiated.
  2. As a first step, a Lambda function triggers an import DAG utility to restore the metadata contents from the backups to the passive Amazon MWAA DR environment. When the imports are complete, the same DAG can un-pause the other Airflow DAGs, making them active for future runs. Any DAG runs that were interrupted during the impairment of the primary environment need to be manually rerun to maintain service level agreements. Future DAG runs are queued to run as per their next configured schedule.

Best practices to improve resiliency of Amazon MWAA

To enhance the resiliency of your Amazon MWAA environment and ensure smooth disaster recovery, consider implementing the following best practices:

  • Robust backup and restore mechanisms – Implementing comprehensive backup and restore mechanisms for Amazon MWAA data is essential. Regularly deleting existing metadata based on your organization’s retention policies reduces backup times and makes your Amazon MWAA environment more performant.
  • Automation using IaC – Using automation and orchestration tools such as AWS CloudFormation, the AWS Cloud Development Kit (AWS CDK), or Terraform can streamline the deployment and configuration management of Amazon MWAA environments. This ensures consistency, reproducibility, and faster recovery during DR scenarios.
  • Idempotent DAGs and tasks – In Airflow, a DAG is considered idempotent if rerunning the same DAG with the same inputs multiple times has the same effect as running it only once. Designing idempotent DAGs and keeping tasks atomic decreases recovery time from failures when you have to manually rerun an interrupted DAG in your recovered environment.
  • Regular testing and validation – A robust Amazon MWAA DR strategy should include regular testing and validation exercises. By simulating disaster scenarios, you can identify any gaps in your DR plans, fine-tune processes, and ensure your Amazon MWAA environments are fully recoverable.

Conclusion

In this post, we explored the challenges for Amazon MWAA disaster recovery and discussed best practices to improve resiliency. We examined two DR strategy solutions: backup and restore and active-passive environments with periodic data synchronization. By implementing these solutions and following best practices, you can protect your Amazon MWAA environments, minimize downtime, and mitigate the impact of disasters. Regular testing, validation, and adaptation to evolving requirements are crucial for an effective Amazon MWAA DR strategy. By continuously evaluating and refining your disaster recovery plans, you can ensure the resilience and uninterrupted operation of your Amazon MWAA environments, even in the face of unforeseen events.

For additional details and code examples on Amazon MWAA, refer to the Amazon MWAA User Guide and the Amazon MWAA examples GitHub repo.


About the Authors

Parnab Basak is a Senior Solutions Architect and a Serverless Specialist at AWS. He specializes in creating new solutions that are cloud native using modern software development practices like serverless, DevOps, and analytics. Parnab works closely in the analytics and integration services space helping customers adopt AWS services for their workflow orchestration needs.

Chandan Rupakheti is a Solutions Architect and a Serverless Specialist at AWS. He is a passionate technical leader, researcher, and mentor with a knack for building innovative solutions in the cloud and bringing stakeholders together in their cloud journey. Outside his professional life, he loves spending time with his family and friends besides listening and playing music.

Vinod Jayendra is a Enterprise Support Lead in ISV accounts at Amazon Web Services, where he helps customers in solving their architectural, operational, and cost optimization challenges. With a particular focus on Serverless technologies, he draws from his extensive background in application development to deliver top-tier solutions. Beyond work, he finds joy in quality family time, embarking on biking adventures, and coaching youth sports team.

Rupesh Tiwari is a Senior Solutions Architect at AWS in New York City, with a focus on Financial Services. He has over 18 years of IT experience in the finance, insurance, and education domains, and specializes in architecting large-scale applications and cloud-native big data workloads. In his spare time, Rupesh enjoys singing karaoke, watching comedy TV series, and creating joyful moments with his family.

Detect, mask, and redact PII data using AWS Glue before loading into Amazon OpenSearch Service

Post Syndicated from Michael Hamilton original https://aws.amazon.com/blogs/big-data/detect-mask-and-redact-pii-data-using-aws-glue-before-loading-into-amazon-opensearch-service/

Many organizations, small and large, are working to migrate and modernize their analytics workloads on Amazon Web Services (AWS). There are many reasons for customers to migrate to AWS, but one of the main reasons is the ability to use fully managed services rather than spending time maintaining infrastructure, patching, monitoring, backups, and more. Leadership and development teams can spend more time optimizing current solutions and even experimenting with new use cases, rather than maintaining the current infrastructure.

With the ability to move fast on AWS, you also need to be responsible with the data you’re receiving and processing as you continue to scale. These responsibilities include being compliant with data privacy laws and regulations and not storing or exposing sensitive data like personally identifiable information (PII) or protected health information (PHI) from upstream sources.

In this post, we walk through a high-level architecture and a specific use case that demonstrates how you can continue to scale your organization’s data platform without needing to spend large amounts of development time to address data privacy concerns. We use AWS Glue to detect, mask, and redact PII data before loading it into Amazon OpenSearch Service.

Solution overview

The following diagram illustrates the high-level solution architecture. We have defined all layers and components of our design in line with the AWS Well-Architected Framework Data Analytics Lens.

os_glue_architecture

The architecture is comprised of a number of components:

Source data

Data may be coming from many tens to hundreds of sources, including databases, file transfers, logs, software as a service (SaaS) applications, and more. Organizations may not always have control over what data comes through these channels and into their downstream storage and applications.

Ingestion: Data lake batch, micro-batch, and streaming

Many organizations land their source data into their data lake in various ways, including batch, micro-batch, and streaming jobs. For example, Amazon EMR, AWS Glue, and AWS Database Migration Service (AWS DMS) can all be used to perform batch and or streaming operations that sink to a data lake on Amazon Simple Storage Service (Amazon S3). Amazon AppFlow can be used to transfer data from different SaaS applications to a data lake. AWS DataSync and AWS Transfer Family can help with moving files to and from a data lake over a number of different protocols. Amazon Kinesis and Amazon MSK also have capabilities to stream data directly to a data lake on Amazon S3.

S3 data lake

Using Amazon S3 for your data lake is in line with the modern data strategy. It provides low-cost storage without sacrificing performance, reliability, or availability. With this approach, you can bring compute to your data as needed and only pay for capacity it needs to run.

In this architecture, raw data can come from a variety of sources (internal and external), which may contain sensitive data.

Using AWS Glue crawlers, we can discover and catalog the data, which will build the table schemas for us, and ultimately make it straightforward to use AWS Glue ETL with the PII transform to detect and mask or and redact any sensitive data that may have landed in the data lake.

Business context and datasets

To demonstrate the value of our approach, let’s imagine you’re part of a data engineering team for a financial services organization. Your requirements are to detect and mask sensitive data as it is ingested into your organization’s cloud environment. The data will be consumed by downstream analytical processes. In the future, your users will be able to safely search historical payment transactions based on data streams collected from internal banking systems. Search results from operation teams, customers, and interfacing applications must be masked in sensitive fields.

The following table shows the data structure used for the solution. For clarity, we have mapped raw to curated column names. You’ll notice that multiple fields within this schema are considered sensitive data, such as first name, last name, Social Security number (SSN), address, credit card number, phone number, email, and IPv4 address.

Raw Column Name Curated Column Name Type
c0 first_name string
c1 last_name string
c2 ssn string
c3 address string
c4 postcode string
c5 country string
c6 purchase_site string
c7 credit_card_number string
c8 credit_card_provider string
c9 currency string
c10 purchase_value integer
c11 transaction_date date
c12 phone_number string
c13 email string
c14 ipv4 string

Use case: PII batch detection before loading to OpenSearch Service

Customers who implement the following architecture have built their data lake on Amazon S3 to run different types of analytics at scale. This solution is suitable for customers who don’t require real-time ingestion to OpenSearch Service and plan to use data integration tools that run on a schedule or are triggered through events.

batch_architecture

Before data records land on Amazon S3, we implement an ingestion layer to bring all data streams reliably and securely to the data lake. Kinesis Data Streams is deployed as an ingestion layer for accelerated intake of structured and semi-structured data streams. Examples of these are relational database changes, applications, system logs, or clickstreams. For change data capture (CDC) use cases, you can use Kinesis Data Streams as a target for AWS DMS. Applications or systems generating streams containing sensitive data are sent to the Kinesis data stream via one of the three supported methods: the Amazon Kinesis Agent, the AWS SDK for Java, or the Kinesis Producer Library. As a last step, Amazon Kinesis Data Firehose helps us reliably load near-real-time batches of data into our S3 data lake destination.

The following screenshot shows how data flows through Kinesis Data Streams via the Data Viewer and retrieves sample data that lands on the raw S3 prefix. For this architecture, we followed the data lifecycle for S3 prefixes as recommended in Data lake foundation.

kinesis raw data

As you can see from the details of the first record in the following screenshot, the JSON payload follows the same schema as in the previous section. You can see the unredacted data flowing into the Kinesis data stream, which will be obfuscated later in subsequent stages.

raw_json

After the data is collected and ingested into Kinesis Data Streams and delivered to the S3 bucket using Kinesis Data Firehose, the processing layer of the architecture takes over. We use the AWS Glue PII transform to automate detection and masking of sensitive data in our pipeline. As shown in the following workflow diagram, we took a no-code, visual ETL approach to implement our transformation job in AWS Glue Studio.

glue studio nodes

First, we access the source Data Catalog table raw from the pii_data_db database. The table has the schema structure presented in the previous section. To keep track of the raw processed data, we used job bookmarks.

glue catalog

We use the AWS Glue DataBrew recipes in the AWS Glue Studio visual ETL job to transform two date attributes to be compatible with OpenSearch expected formats. This allows us to have a full no-code experience.

We use the Detect PII action to identify sensitive columns. We let AWS Glue determine this based on selected patterns, detection threshold, and sample portion of rows from the dataset. In our example, we used patterns that apply specifically to the United States (such as SSNs) and may not detect sensitive data from other countries. You may look for available categories and locations applicable to your use case or use regular expressions (regex) in AWS Glue to create detection entities for sensitive data from other countries.

It’s important to select the correct sampling method that AWS Glue offers. In this example, it’s known that the data coming in from the stream has sensitive data in every row, so it’s not necessary to sample 100% of the rows in the dataset. If you have a requirement where no sensitive data is allowed to downstream sources, consider sampling 100% of the data for the patterns you chose, or scan the entire dataset and act on each individual cell to ensure all sensitive data is detected. The benefit you get from sampling is reduced costs because you don’t have to scan as much data.

PII Options

The Detect PII action allows you to select a default string when masking sensitive data. In our example, we use the string **********.

selected_options

We use the apply mapping operation to rename and remove unnecessary columns such as ingestion_year, ingestion_month, and ingestion_day. This step also allows us to change the data type of one of the columns (purchase_value) from string to integer.

schema

From this point on, the job splits into two output destinations: OpenSearch Service and Amazon S3.

Our provisioned OpenSearch Service cluster is connected via the OpenSearch built-in connector for Glue. We specify the OpenSearch Index we’d like to write to and the connector handles the credentials, domain and port. In the screen shot below, we write to the specified index index_os_pii.

opensearch config

We store the masked dataset in the curated S3 prefix. There, we have data normalized to a specific use case and safe consumption by data scientists or for ad hoc reporting needs.

opensearch target s3 folder

For unified governance, access control, and audit trails of all datasets and Data Catalog tables, you can use AWS Lake Formation. This helps you restrict access to the AWS Glue Data Catalog tables and underlying data to only those users and roles who have been granted necessary permissions to do so.

After the batch job runs successfully, you can use OpenSearch Service to run search queries or reports. As shown in the following screenshot, the pipeline masked sensitive fields automatically with no code development efforts.

You can identify trends from the operational data, such as the amount of transactions per day filtered by credit card provider, as shown in the preceding screenshot. You can also determine the locations and domains where users make purchases. The transaction_date attribute helps us see these trends over time. The following screenshot shows a record with all of the transaction’s information redacted appropriately.

json masked

For alternate methods on how to load data into Amazon OpenSearch, refer to Loading streaming data into Amazon OpenSearch Service.

Furthermore, sensitive data can also be discovered and masked using other AWS solutions. For example, you could use Amazon Macie to detect sensitive data inside an S3 bucket, and then use Amazon Comprehend to redact the sensitive data that was detected. For more information, refer to Common techniques to detect PHI and PII data using AWS Services.

Conclusion

This post discussed the importance of handling sensitive data within your environment and various methods and architectures to remain compliant while also allowing your organization to scale quickly. You should now have a good understanding of how to detect, mask, or redact and load your data into Amazon OpenSearch Service.


About the authors

Michael Hamilton is a Sr Analytics Solutions Architect focusing on helping enterprise customers modernize and simplify their analytics workloads on AWS. He enjoys mountain biking and spending time with his wife and three children when not working.

Daniel Rozo is a Senior Solutions Architect with AWS supporting customers in the Netherlands. His passion is engineering simple data and analytics solutions and helping customers move to modern data architectures. Outside of work, he enjoys playing tennis and biking.
How to customize access tokens in Amazon Cognito user pools

Post Syndicated from Edward Sun original https://aws.amazon.com/blogs/security/how-to-customize-access-tokens-in-amazon-cognito-user-pools/

With Amazon Cognito, you can implement customer identity and access management (CIAM) into your web and mobile applications. You can add user authentication and access control to your applications in minutes.

In this post, I introduce you to the new access token customization feature for Amazon Cognito user pools and show you how to use it. Access token customization is included in the advanced security features (ASF) of Amazon Cognito. Note that ASF is subject to additional pricing as described on the Amazon Cognito pricing page.

What is access token customization?

When a user signs in to your app, Amazon Cognito verifies their sign-in information, and if the user is authenticated successfully, returns the ID, access, and refresh tokens. The access token, which uses the JSON Web Token (JWT) format following the RFC7519 standard, contains claims in the token payload that identify the principal being authenticated, and session attributes such as authentication time and token expiration time. More importantly, the access token also contains authorization attributes in the form of user group memberships and OAuth scopes. Your applications or API resource servers can evaluate the token claims to authorize specific actions on behalf of users.

With access token customization, you can add application-specific claims to the standard access token and then make fine-grained authorization decisions to provide a differentiated end-user experience. You can refine the original scope claims to further restrict access to your resources and enforce the least privileged access. You can also enrich access tokens with claims from other sources, such as user subscription information stored in an Amazon DynamoDB table. Your application can use this enriched claim to determine the level of access and content available to the user. This reduces the need to build a custom solution to look up attributes in your application’s code, thereby reducing application complexity, improving performance, and smoothing the integration experience with downstream applications.

How do I use the access token customization feature?

Amazon Cognito works with AWS Lambda functions to modify your user pool’s authentication behavior and end-user experience. In this section, you’ll learn how to configure a pre token generation Lambda trigger function and invoke it during the Amazon Cognito authentication process. I’ll also show you an example function to help you write your own Lambda function.

Lambda trigger flow

During a user authentication, you can choose to have Amazon Cognito invoke a pre token generation trigger to enrich and customize your tokens.

Figure 1: Pre token generation trigger flow

Figure 1: Pre token generation trigger flow

Figure 1 illustrates the pre token generation trigger flow. This flow has the following steps:

  1. An end user signs in to your app and authenticates with an Amazon Cognito user pool.
  2. After the user completes the authentication, Amazon Cognito invokes the pre token generation Lambda trigger, and sends event data to your Lambda function, such as userAttributes and scopes, in a pre token generation trigger event.
  3. Your Lambda function code processes token enrichment logic, and returns a response event to Amazon Cognito to indicate the claims that you want to add or suppress.
  4. Amazon Cognito vends a customized JWT to your application.

The pre token generation trigger flow supports OAuth 2.0 grant types, such as the authorization code grant flow and implicit grant flow, and also supports user authentication through the AWS SDK.

Enable access token customization

Your Amazon Cognito user pool delivers two different versions of the pre token generation trigger event to your Lambda function. Trigger event version 1 includes userAttributes, groupConfiguration, and clientMetadata in the event request, which you can use to customize ID token claims. Trigger event version 2 adds scope in the event request, which you can use to customize scopes in the access token in addition to customizing other claims.

In this section, I’ll show you how to update your user pool to trigger event version 2 and enable access token customization.

To enable access token customization

  1. Open the Cognito user pool console, and then choose User pools.
  2. Choose the target user pool for token customization.
  3. On the User pool properties tab, in the Lambda triggers section, choose Add Lambda trigger.
  4. Figure 2: Add Lambda trigger

    Figure 2: Add Lambda trigger

  5. In the Lambda triggers section, do the following:
    1. For Trigger type, select Authentication.
    2. For Authentication, select Pre token generation trigger.
    3. For Trigger event version, select Basic features + access token customization – Recommended. If this option isn’t available to you, make sure that you have enabled advanced security features. You must have advanced security features enabled to access this option.
  6. Figure 3: Select Lambda trigger

    Figure 3: Select Lambda trigger

  7. Select your Lambda function and assign it as the pre token generation trigger. Then choose Add Lambda trigger.
  8. Figure 4: Add Lambda trigger

    Figure 4: Add Lambda trigger

Example pre token generation trigger

Now that you have enabled access token customization, I’ll walk you through a code example of the pre token generation Lambda trigger, and the version 2 trigger event. This code example examines the trigger event request, and adds a new custom claim and a custom OAuth scope in the response for Amazon Cognito to customize the access token to suit various authorization scheme.

Here is an example version 2 trigger event. The event request contains the user attributes from the Amazon Cognito user pool, the original scope claims, and the original group configurations. It has two custom attributes—membership and location—which are collected during the user registration process and stored in the Cognito user pool.

{
  "version": "2",
  "triggerSource": "TokenGeneration_HostedAuth",
  "region": "us-east-1",
  "userPoolId": "us-east-1_01EXAMPLE",
  "userName": "mytestuser",
  "callerContext": {
    "awsSdkVersion": "aws-sdk-unknown-unknown",
    "clientId": "1example23456789"
  },
  "request": {
    "userAttributes": {
      "sub": "a1b2c3d4-5678-90ab-cdef-EXAMPLE11111",
      "cognito:user_status": "CONFIRMED",
      "email": "[email protected]",
      "email_verified": "true",
      "custom:membership": "Premium",
      "custom:location": "USA"
    },
    "groupConfiguration": {
      "groupsToOverride": [],
      "iamRolesToOverride": [],
      "preferredRole": null
    },
    "scopes": [
      "openid",
      "profile",
      "email"
    ]
  },
  "response": {
    "claimsAndScopeOverrideDetails": null
  }
}

In the following code example, I transformed the user’s location attribute and membership attribute to add a custom claim and a custom scope. I used the claimsToAddOrOverride field to create a new custom claim called demo:membershipLevel with a membership value of Premium from the event request. I also constructed a new scope with the value of membership:USA.Premium through the scopesToAdd claim, and added the new claim and scope in the event response.

export const handler = function(event, context) {
  // Retrieve user attribute from event request
  const userAttributes = event.request.userAttributes;
  // Add scope to event response
  event.response = {
    "claimsAndScopeOverrideDetails": {
      "idTokenGeneration": {},
      "accessTokenGeneration": {
        "claimsToAddOrOverride": {
          "demo:membershipLevel": userAttributes['custom:membership']
        },
        "scopesToAdd": ["membership:" + userAttributes['custom:location'] + "." + userAttributes['custom:membership']]
      }
    }
  };
  // Return to Amazon Cognito
  context.done(null, event);
};

With the preceding code, the Lambda trigger sends the following response back to Amazon Cognito to indicate the customization that was needed for the access tokens.

"response": {
  "claimsAndScopeOverrideDetails": {
    "idTokenGeneration": {},
    "accessTokenGeneration": {
      "claimsToAddOrOverride": {
        "demo:membershipLevel": "Premium"
      },
      "scopesToAdd": [
        "membership:USA.Premium"
      ]
    }
  }
}

Then Amazon Cognito issues tokens with these customizations at runtime:

{
  "sub": "a1b2c3d4-5678-90ab-cdef-EXAMPLE11111",
  "iss": "https://cognito-idp.us-east-1.amazonaws.com/us-east-1_01EXAMPLE",
  "version": 2,
  "client_id": "1example23456789",
  "event_id": "01faa385-562d-4730-8c3b-458e5c8f537b",
  "token_use": "access",
  "demo:membershipLevel": "Premium",
  "scope": "openid profile email membership:USA.Premium",
  "auth_time": 1702270800,
  "exp": 1702271100,
  "iat": 1702270800,
  "jti": "d903dcdf-8c73-45e3-bf44-51bf7c395e06",
  "username": "mytestuser"
}

Your application can then use the newly-minted, custom scope and claim to authorize users and provide them with a personalized experience.

Considerations and best practices

There are four general considerations and best practices that you can follow:

  1. Some claims and scopes aren’t customizable. For example, you can’t customize claims such as auth_time, iss, and sub, or scopes such as aws.cognito.signin.user.admin. For the full list of excluded claims and scopes, see the Excluded claims and scopes.
  2. Work backwards from authorization. When you customize access tokens, you should start with your existing authorization schema and then decide whether to customize the scopes or claims, or both. Standard OAuth based authorization scenarios, such as Amazon API Gateway authorizers, typically use custom scopes to provide access. However, if you have complex or fine-grained authorization requirements, then you should consider using both scopes and custom claims to pass additional contextual data to the application or to a policy-based access control service such as Amazon Verified Permission.
  3. Establish governance in token customization. You should have a consistent company engineering policy to provide nomenclature guidance for scopes and claims. A syntax standard promotes globally unique variables and avoids a name collision across different application teams. For example, Application X at AnyCompany can choose to name their scope as ac.appx.claim_name, where ac represents AnyCompany as a global identifier and appx.claim_name represents Application X’s custom claim.
  4. Be aware of limits. Because tokens are passed through various networks and systems, you need to be aware of potential token size limitations in your systems. You should keep scope and claim names as short as possible, while still being descriptive.

Conclusion

In this post, you learned how to integrate a pre token generation Lambda trigger with your Amazon Cognito user pool to customize access tokens. You can use the access token customization feature to provide differentiated services to your end users based on claims and OAuth scopes. For more information, see pre token generation Lambda trigger in the Amazon Cognito Developer Guide.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Edward Sun

Edward Sun

Edward is a Security Specialist Solutions Architect focused on identity and access management. He loves helping customers throughout their cloud transformation journey with architecture design, security best practices, migration, and cost optimizations. Outside of work, Edward enjoys hiking, golfing, and cheering for his alma mater, the Georgia Bulldogs.

Enable metric-based and scheduled scaling for Amazon Managed Service for Apache Flink

Post Syndicated from Francisco Morillo original https://aws.amazon.com/blogs/big-data/enable-metric-based-and-scheduled-scaling-for-amazon-managed-service-for-apache-flink/

Thousands of developers use Apache Flink to build streaming applications to transform and analyze data in real time. Apache Flink is an open source framework and engine for processing data streams. It’s highly available and scalable, delivering high throughput and low latency for the most demanding stream-processing applications. Monitoring and scaling your applications is critical to keep your applications running successfully in a production environment.

Amazon Managed Service for Apache Flink is a fully managed service that reduces the complexity of building and managing Apache Flink applications. Amazon Managed Service for Apache Flink manages the underlying Apache Flink components that provide durable application state, metrics, logs, and more.

In this post, we show a simplified way to automatically scale up and down the number of KPUs (Kinesis Processing Units; 1 KPU is 1 vCPU and 4 GB of memory) of your Apache Flink applications with Amazon Managed Service for Apache Flink. We show you how to scale by using metrics such as CPU, memory, backpressure, or any custom metric of your choice. Additionally, we show how to perform scheduled scaling, allowing you to adjust your application’s capacity at specific times, particularly when dealing with predictable workloads. We also share an AWS CloudFormation utility to help you implement auto scaling quickly with your Amazon Managed Service for Apache Flink applications.

Metric-based scaling

This section describes how to implement a scaling solution for Amazon Managed Service for Apache Flink based on Amazon CloudWatch metrics. Amazon Managed Service for Apache Flink comes with an auto scaling option out of the box that scales out when container CPU utilization is above 75% for 15 minutes. This works well for many use cases; however, for some applications, you may need to scale based on a different metric, or trigger the scaling action at a certain point in time or by a different factor. You can customize your scaling policies and save costs by right-sizing your Amazon Managed Apache Flink applications the deploying this solution.

To perform metric-based scaling, we use CloudWatch alarms, Amazon EventBridge, AWS Step Functions, and AWS Lambda. You can choose from metrics coming from the source such as Amazon Kinesis Data Streams or Amazon Managed Streaming for Apache Kafka (Amazon MSK), or metrics from the Amazon Managed Service for Apache Flink application. You can find these components in the CloudFormation template in the GitHub repo.

The following diagram shows how to scale an Amazon Managed Service for Apache Flink application in response to a CloudWatch alarm.

This solution uses the metric selected and creates two CloudWatch alarms that, depending on the threshold you use, trigger a rule in EventBridge to start running a Step Functions state machine. The following diagram illustrates the state machine workflow.

Note: Amazon Kinesis Data Analytics was renamed to Amazon Managed Service for Apache Flink August 2023

The Step Functions workflow consists of the following steps:

  1. The state machine describes the Amazon Managed Service for Apache Flink application, which will provide information related to the current number of KPUs in the application, as well if the application is being updated or is it running.
  2. The state machine invokes a Lambda function that, depending on which alarm was triggered, will scale the application up or down, following the parameters set in the CloudFormation template. When scaling the application, it will use the increase factor (either add/subtract or multiple/divide based on that factor) defined in the CloudFormation template. You can have different factors for scaling in or out. If you want to take a more cautious approach to scaling, you can use add/subtract and use an increase factor for scaling in/out of 1.
  3. If the application has reached the maximum or minimum number of KPUs set in the parameters of the CloudFormation template, the workflow stops. Keep in mind that Amazon Managed Service for Apache Flink applications have a default maximum of 64 KPUs (you can request to increase this limit). Do not specify a maximum value above 64 KPUs if you have not requested to increase the quota, because the scaling solution will get stuck by failing to update.
  4. If the workflow continues, because the allocated KPUs haven’t reached the maximum or minimum values, the workflow will wait for a period of time you specify, and then describe the application and see if it has finished updating.
  5. The workflow will continue to wait until the application has finished updating. When the application is updated, the workflow will wait for a period of time you specify in the CloudFormation template, to allow the metric to fall within the threshold and have the CloudWatch rule change from ALARM state to OK.
  6. If the metric is still in ALARM state, the workflow will start again and continue to scale the application either up or down. If the metric is in OK state, the workflow will stop.

For applications that read from a Kinesis Data Streams source, you can use the metric millisBehindLatest. If using a Kafka source, you can use records lag max for scaling events. These metrics capture how far behind your application is from the head of the stream. You can also use a custom metric that you have registered in your Apache Flink applications.

The sample CloudFormation template allows you to select one of the following metrics:

  • Amazon Managed Service for Apache Flink application metrics – Requires an application name:
    • ContainerCPUUtilization – Overall percentage of CPU utilization across task manager containers in the Flink application cluster.
    • ContainerMemoryUtilization – Overall percentage of memory utilization across task manager containers in the Flink application cluster.
    • BusyTimeMsPerSecond – Time in milliseconds the application is busy (neither idle nor back pressured) per second.
    • BackPressuredTimeMsPerSecond – Time in milliseconds the application is back pressured per second.
    • LastCheckpointDuration – Time in milliseconds it took to complete the last checkpoint.
  • Kinesis Data Streams metrics – Requires the data stream name:
    • MillisBehindLatest – The number of milliseconds the consumer is behind the head of the stream, indicating how far behind the current time the consumer is.
    • IncomingRecords – The number of records successfully put to the Kinesis data stream over the specified time period. If no records are coming, this metric will be null and you won’t be able to scale down.
  • Amazon MSK metrics – Requires the cluster name, topic name, and consumer group name):
    • MaxOffsetLag – The maximum offset lag across all partitions in a topic.
    • SumOffsetLag – The aggregated offset lag for all the partitions in a topic.
    • EstimatedMaxTimeLag – The time estimate (in seconds) to drain MaxOffsetLag.
  • Custom metrics – Metrics you can define as part of your Apache Flink applications. Most common metrics are counters (continuously increase) or gauges (can be updated with last value). For this solution, you need to add the kinesisAnalytics dimension to the metric group. You also need to provide the custom metric name as a parameter in the CloudFormation template. If you need to use more dimensions in your custom metric, you need to modify the CloudWatch alarm so it’s able to use your specific metric. For more information on custom metrics, see Using Custom Metrics with Amazon Managed Service for Apache Flink.

The CloudFormation template deploys the resources as well as the auto scaling code. You only need to specify the name of the Amazon Managed Service for Apache Flink application, the metric to which you want to scale your application in or out, and the thresholds for triggering an alarm. The solution by default will use the average aggregation for metrics and a period duration of 60 seconds for each data point. You can configure the evaluation periods and data points to alarm when defining the CloudFormation template.

Scheduled scaling

This section describes how to implement a scaling solution for Amazon Managed Service for Apache Flink based on a schedule. To perform scheduled scaling, we use EventBridge and Lambda, as illustrated in the following figure.

These components are available in the CloudFormation template in the GitHub repo.

The EventBridge scheduler is triggered based on the parameters set when deploying the CloudFormation template. You define the KPU of the applications when running at peak times, as well as the KPU for non-peak times. The application runs with those KPU parameters depending on the time of day.

As with the previous example for metric-based scaling, the CloudFormation template deploys the resources and scaling code required. You only need to specify the name of the Amazon Managed Service for Apache Flink application and the schedule for the scaler to modify the application to the set number of KPUs.

Considerations for scaling Flink applications using metric-based or scheduled scaling

Be aware of the following when considering these solutions:

  • When scaling Amazon Managed Service for Apache Flink applications in or out, you can choose to either increase the overall application parallelism or modify the parallelism per KPU. The latter allows you to set the number of parallel tasks that can be scheduled per KPU. This sample only updates the overall parallelism, not the parallelism per KPU.
  • If SnapshotsEnabled is set to true in ApplicationSnapshotConfiguration, Amazon Managed Service for Apache Flink will automatically pause the application, take a snapshot, and then restore the application with the updated configuration whenever it is updated or scaled. This process may result in downtime for the application, depending on the state size, but there will be no data loss. When using metric-based scaling, you have to choose a minimum and a maximum threshold of KPU the application can have. Depending on by how much you perform the scaling, if the new desired KPU is bigger or lower than your thresholds, the solution will update the KPUs to be equal to your thresholds.
  • When using metric-based scaling, you also have to choose a cooling down period. This is the amount of time you want your application to wait after being updated, to see if the metric has gone from ALARM status to OK status. This value depends on how long are you willing to wait before another scaling event to occur.
  • With the metric-based scaling solution, you are limited to choosing the metrics that are listed in the CloudFormation template. However, you can modify the alarms to use any available metric in CloudWatch.
  • If your application is required to run without interruptions for periods of time, we recommend using scheduled scaling, to limit scaling to non-critical times.

Summary

In this post, we covered how you can enable custom scaling for Amazon Managed Service for Apache Flink applications using enhanced monitoring features from CloudWatch integrated with Step Functions and Lambda. We also showed how you can configure a schedule to scale an application using EventBridge. Both of these samples and many more can be found in the GitHub repo.


About the Authors

Deepthi Mohan is a Principal PMT on the Amazon Managed Service for Apache Flink team.

Francisco Morillo is a Streaming Solutions Architect at AWS. Francisco works with AWS customers, helping them design real-time analytics architectures using AWS services, supporting Amazon Managed Streaming for Apache Kafka (Amazon MSK) and Amazon Managed Service for Apache Flink.

Achieve high availability in Amazon OpenSearch Multi-AZ with Standby enabled domains: A deep dive into failovers

Post Syndicated from Anshu Agarwal original https://aws.amazon.com/blogs/big-data/achieve-high-availability-in-amazon-opensearch-multi-az-with-standby-enabled-domains-a-deep-dive-into-failovers/

Amazon OpenSearch Service recently introduced Multi-AZ with Standby, a deployment option designed to provide businesses with enhanced availability and consistent performance for critical workloads. With this feature, managed clusters can achieve 99.99% availability while remaining resilient to zonal infrastructure failures.

In this post, we explore how search and indexing works with Multi-AZ with Standby and delve into the underlying mechanisms that contribute to its reliability, simplicity, and fault tolerance.

Background

Multi-AZ with Standby deploys OpenSearch Service domain instances across three Availability Zones, with two zones designated as active and one as standby. This configuration ensures consistent performance, even in the event of zonal failures, by maintaining the same capacity across all zones. Importantly, this standby zone follows a statically stable design, eliminating the need for capacity provisioning or data movement during failures.

During regular operations, the active zone handles coordinator traffic for both read and write requests, as well as shard query traffic. The standby zone, on the other hand, only receives replication traffic. OpenSearch Service utilizes a synchronous replication protocol for write requests. This enables the service to promptly promote a standby zone to active status in the event of a failure (mean time to failover <= 1 minute), known as a zonal failover. The previously active zone is then demoted to standby mode, and recovery operations commence to restore its healthy state.

Search traffic routing and failover to guarantee high availability

In an OpenSearch Service domain, a coordinator is any node that handles HTTP(S) requests, especially indexing and search requests. In a Multi-AZ with Standby domain, the data nodes in the active zone act as coordinators for search requests.

During the query phase of a search request, the coordinator determines the shards to be queried and sends a request to the data node hosting the shard copy. The query is run locally on each shard and matched documents are returned to the coordinator node. The coordinator node, which is responsible for sending the request to nodes containing shard copies, runs the process in two steps. First, it creates an iterator that defines the order in which nodes need to be queried for a shard copy so that traffic is uniformly distributed across shard copies. Subsequently, the request is sent to the relevant nodes.

In order to create an ordered list of nodes to be queried for a shard copy, the coordinator node uses various algorithms. These algorithms include round-robin selection, adaptive replica selection, preference-based shard routing, and weighted round-robin.

For Multi-AZ with Standby, the weighted round-robin algorithm is used for shard copy selection. In this approach, active zones are assigned a weight of 1, and the standby zone is assigned a weight of 0. This ensures that no read traffic is sent to data nodes in the standby Availability Zone.

The weights are stored in cluster state metadata as a JSON object:

"weighted_shard_routing": {
    "awareness": {
        "zone": {
            "us-east-1b": 0,
            "us-east-1d": 1,
            "us-east-1c": 1
         }
     },
     "_version": 3
}

As shown in the following screenshot, the us-east-1b Region has its zone status as StandBy, indicating that the data nodes in this Availability Zone are in standby state and don’t receive search or indexing requests from the load balancer.

Availability Zone status in AWS Console

To maintain steady-state operations, the standby Availability Zone is rotated every 30 minutes, ensuring all network parts are covered across Availability Zones. This proactive approach verifies the availability of read paths, further enhancing the system’s resilience during potential failures. The following diagram illustrates this architecture.

Steady State Operation

In the preceding diagram, Zone-C has a weighted round-robin weight set to zero. This ensures that the data nodes in the standby zone don’t receive any indexing or search traffic. When the coordinator queries data nodes for shard copies, it uses a weighted round-robin weight to decide on the order in which nodes to be queried. Because the weight is zero for the standby Availability Zone, coordinator requests are not sent.

In an OpenSearch Service cluster, the active and standby zones can be checked at any time using Availability Zone rotation metrics, as shown in the following screenshot.

Availability Zone rotation metrics

During zonal outages, the standby Availability Zone seamlessly switches to fail-open mode for search requests. This means that the shard query traffic is routed to all Availability Zones, even those in standby, when a healthy shard copy is unavailable in the active Availability Zone. This fail-open approach safeguards search requests from disruption during failures, ensuring continuous service. The following diagram illustrates this architecture.

Read Failover during Zonal Failure

In the preceding diagram, during the steady state, the shard query traffic is sent to the data node in the active Availability Zones (Zone-A and Zone-B). Due to node failures in Zone-A, the standby Availability Zone (Zone-C) fails open to take shard query traffic so that there isn’t any impact to the search requests. Eventually, Zone-A is detected as unhealthy and the read failover switches the standby to Zone-A.

How failover ensures high availability during write impairment

The OpenSearch Service replication model follows a primary backup model, characterized by its synchronous nature, where acknowledgement from all shard copies is necessary before a write request can be acknowledged to the user. One notable drawback of this replication model is its susceptibility to slowdowns in the event of any impairment in the write path. These systems rely on an active leader node to identify failures or delays and then broadcast this information to all nodes. The duration it takes to detect these issues (mean time to detect) and subsequently resolve them (mean time to repair) largely determines how long the system will operate in an impaired state. Additionally, any networking event that affects inter-zone communications can significantly impede write requests due to the synchronous nature of replication.

OpenSearch Service utilizes an internal node-to-node communication protocol for replicating write traffic and coordinating metadata updates through an elected leader. Consequently, putting the zone experiencing stress in standby wouldn’t effectively address the issue of write impairment.

Zonal write failover: Cutting off inter-zone replication traffic

For Multi-AZ with Standby, to mitigate potential performance issues caused during unforeseen events like zonal failures and networking events, zonal write failover is an effective approach. This approach involves graceful removal of nodes in the impacted zone from the cluster, effectively cutting off ingress and egress traffic between zones. By severing the inter-zone replication traffic, the impact of zonal failures can be contained within the affected zone. This provides a more predictable experience for customers and ensures that the system continues to operate reliably.

Graceful write failover

The orchestration of a write failover within OpenSearch Service is carried out by the elected leader node through a well-defined mechanism. This mechanism involves a consensus protocol for cluster state publication, ensuring unanimous agreement among all nodes to designate a single zone (at all times) for decommissioning. Importantly, metadata related to the affected zone is replicated across all nodes to ensure its persistence, even during a full restart in the event of an outage.

Furthermore, the leader node ensures a smooth and graceful transition by initially placing the nodes in the impacted zones on standby for a duration of 5 minutes before initiating I/O fencing. This deliberate approach prevents any new coordinator traffic or shard query traffic from being directed to the nodes within the impacted zone. This, in turn, allow these nodes to complete their ongoing tasks gracefully and gradually handle any inflight requests before being taken out of service. The following diagram illustrates this architecture.

Write Failover during Networking Event

In the process of implementing a write failover for a leader node, OpenSearch Service follows these key steps:

  • Leader abdication – If the leader node happens to be located in a zone scheduled for write failover, the system ensures that the leader node voluntarily steps down from its leadership role. This abdication is carried out in a controlled manner, and the entire process is handed over to another eligible node, which then takes charge of the actions required.
  • Prevent reelection of to-be-decommissioned leader – To prevent the reelection of a leader from a zone marked for write failover, when the eligible leader node initiates the write failover action, it takes measures to ensure that any to-be-decommissioned leader nodes do not participate in any further elections. This is achieved by excluding the to-be-decommissioned leader node from the voting configuration, effectively preventing it from voting during any critical phase of the cluster’s operation.

Metadata related to the write failover zone is stored within the cluster state, and this information is published to all nodes in the distributed OpenSearch Service cluster as follows:

"decommissionedAttribute": {
    "awareness": {
        "zone": "us-east-1c"
     },
     "status": "successful",
     "requestID": "FLoyf5v9RVSsaAquRNKxIw"
}

The following screenshot depicts that during a networking slowdown in a zone, write failover helps recover availability.

Write Failover helps recovering availability

Zonal recovery after write failover

The process of zonal recommissioning plays a crucial role in the recovery phase following a zonal write failover. After the impacted zone has been restored and is considered stable, the nodes that were previously decommissioned will rejoin the cluster. This recommissioning typically occurs within a time frame of 2 minutes after the zone has been recommissioned.

This enables them to synchronize with their peer nodes and initiates the recovery process for replica shards, effectively restoring the cluster to its desired state.

Conclusion

The introduction of OpenSearch Service Multi-AZ with Standby provides businesses with a powerful solution to achieve high availability and consistent performance for critical workloads. With this deployment option, businesses can enhance their infrastructure’s resilience, simplify cluster configuration and management, and enforce best practices. With features like weighted round-robin shard copy selection, proactive failover mechanisms, and fail-open standby Availability Zones, OpenSearch Service Multi-AZ with Standby ensures a reliable and efficient search experience for demanding enterprise environments.

For more information about Multi-AZ with Standby, refer to Amazon OpenSearch Service Under the Hood: Multi-AZ with Standby.


About the Author


Anshu Agarwal
 is a Senior Software Engineer working on AWS OpenSearch at Amazon Web Services. She is passionate about solving problems related to building scalable and highly reliable systems.

Rishab Nahata
 is a Software Engineer working on OpenSearch at Amazon Web Services. He is fascinated about solving problems in distributed systems. He is active contributor to OpenSearch.

Bukhtawar Khan
is a Principal Engineer working on Amazon OpenSearch Service. He is interested in distributed and autonomous systems. He is an active contributor to OpenSearch.


Ranjith Ramachandra
is an Engineering Manager working on Amazon OpenSearch Service at Amazon Web Services.
Automate Cedar policy validation with AWS developer tools

Post Syndicated from Pontus Palmenäs original https://aws.amazon.com/blogs/security/automate-cedar-policy-validation-with-aws-developer-tools/

Cedar is an open-source language that you can use to authorize policies and make authorization decisions based on those policies. AWS security services including AWS Verified Access and Amazon Verified Permissions use Cedar to define policies. Cedar supports schema declaration for the structure of entity types in those policies and policy validation with that schema.

In this post, we show you how to use developer tools on AWS to implement a build pipeline that validates the Cedar policy files against a schema and runs a suite of tests to isolate the Cedar policy logic. As part of the walkthrough, you will introduce a subtle policy error that impacts permissions to observe how the pipeline tests catch the error. Detecting errors earlier in the development lifecycle is often referred to as shifting left. When you shift security left, you can help prevent undetected security issues during the application build phase.

Scenario

This post extends a hypothetical photo sharing application from the Cedar policy language in action workshop. By using that app, users organize their photos into albums and share them with groups of users. Figure 1 shows the entities from the photo application.

Figure 1: Photo application entities

Figure 1: Photo application entities

For the purpose of this post, the important requirements are that user JohnDoe has view access to the album JaneVacation, which contains two photos that user JaneDoe owns:

  • Photo sunset.jpg has a contest label (indicating that the role PhotoJudge has view access)
  • Photo nightclub.jpg has a private label (indicating that only the owner has access)

Cedar policies separate application permissions from the code that retrieves and displays photos. The following Cedar policy explicitly permits the principal of user JohnDoe to take the action viewPhoto on resources in the album JaneVacation.

permit (
  principal == PhotoApp::User::"JohnDoe",
  action == PhotoApp::Action::"viewPhoto",
  resource in PhotoApp::Album::"JaneVacation"
);

The following Cedar policy forbids non-owners from accessing photos labeled as private, even if other policies permit access. In our example, this policy prevents John Doe from viewing the nightclub.jpg photo (denoted by an X in Figure 1).

forbid (
  principal,
  action,
  resource in PhotoApp::Application::"PhotoApp"
)
when { resource.labels.contains("private") }
unless { resource.owner == principal };

A Cedar authorization request asks the question: Can this principal take this action on this resource in this context? The request also includes attribute and parent information for the entities. If an authorization request is made with the following test data, against the Cedar policies and entity data described earlier, the authorization result should be DENY.

{
  "principal": "PhotoApp::User::\"JohnDoe\"",
  "action": "PhotoApp::Action::\"viewPhoto\"",
  "resource": "PhotoApp::Photo::\"nightclub.jpg\"",
  "context": {}
}

The project test suite uses this and other test data to validate the expected behaviors when policies are modified. An error intentionally introduced into the preceding forbid policy lets the first policy satisfy the request and ALLOW access. That unexpected test result compared to the requirements fails the build.

Developer tools on AWS

With AWS developer tools, you can host code and build, test, and deploy applications and infrastructure. AWS CodeCommit hosts the Cedar policies and a test suite, AWS CodeBuild runs the tests, and AWS CodePipeline automatically runs the CodeBuild job when a CodeCommit repository state change event occurs.

In the following steps, you will create a pipeline, commit policies and tests, run a passing build, and observe how a policy error during validation fails a test case.

Prerequisites

To follow along with this walkthrough, make sure to complete the following prerequisites:

Set up the local environment

The first step is to set up your local environment.

To set up the local environment

  1. Using Git, clone the GitHub repository for this post:
  2. git clone [email protected]:aws-samples/cedar-policy-validation-pipeline.git

  3. Before you commit this source code to a CodeCommit repository, run the test suite locally; this can help you shorten the feedback loop. To run the test suite locally, choose one of the following options:
  4. Option 1: Install Rust and compile the Cedar CLI binary

    1. Install Rust by using the rustup tool.
    2. curl --proto '=https' --tlsv1.2 -sSf https://sh.rustup.rs | sh -s -- -y

    3. Compile the Cedar CLI (version 2.4.2) binary by using cargo.
    4. cargo install [email protected]

    5. Run the cedar_testrunner.sh script, which tests authorize requests by using the Cedar CLI.
    6. cd policystore/tests && ./cedar_testrunner.sh

    Option 2: Run the CodeBuild agent

    1. Locally evaluate the buildspec.yml inside a CodeBuild container image by using the codebuild_build.sh script from aws-codebuild-docker-images with the following parameters:
    2. ./codebuild_build.sh -i public.ecr.aws/codebuild/amazonlinux2-x86_64-standard:5.0 -a .codebuild

Project structure

The policystore directory contains one Cedar policy for each .cedar file. The Cedar schema is defined in the cedarschema.json file. A tests subdirectory contains a cedarentities.json file that represents the application data; its subdirectories (for example, album JaneVacation) represent the test suites. The test suite directories contain individual tests inside their ALLOW and DENY subdirectories, each with one or more JSON files that contain the authorization request that Cedar will evaluate against the policy set. A README file in the tests directory provides a summary of the test cases in the suite.

The cedar_testrunner.sh script runs the Cedar CLI to perform a validate command for each .cedar file against the Cedar schema, outputting either PASS or ERROR. The script also performs an authorize command on each test file, outputting either PASS or FAIL depending on whether the results match the expected authorization decision.

Set up the CodePipeline

In this step, you use AWS CloudFormation to provision the services used in the pipeline.

To set up the pipeline

  1. Navigate to the directory of the cloned repository.

    cd cedar-policy-validation-pipeline

  2. Create a new CloudFormation stack from the template.
    aws cloudformation deploy \
    --template-file template.yml \
    --stack-name cedar-policy-validation \
    --capabilities CAPABILITY_NAMED_IAM

  3. Wait for the message Successfully created/updated stack.

Invoke CodePipeline

The next step is to commit the source code to a CodeCommit repository, and then configure and invoke CodePipeline.

To invoke CodePipeline

  1. Add an additional Git remote named codecommit to the repository that you previously cloned. The following command points the Git remote to the CodeCommit repository that CloudFormation created. The CedarPolicyRepoCloneUrl stack output is the HTTPS clone URL. Replace it with CedarPolicyRepoCloneGRCUrl to use the HTTPS (GRC) clone URL when you connect to CodeCommit with git-remote-codecommit.

    git remote add codecommit $(aws cloudformation describe-stacks --stack-name cedar-policy-validation --query 'Stacks[0].Outputs[?OutputKey==`CedarPolicyRepoCloneUrl`].OutputValue' --output text)

  2. Push the code to the CodeCommit repository. This starts a pipeline run.

    git push codecommit main

  3. Check the progress of the pipeline run.
    aws codepipeline get-pipeline-execution \
    --pipeline-name cedar-policy-validation \
    --pipeline-execution-id $(aws codepipeline list-pipeline-executions --pipeline-name cedar-policy-validation --query 'pipelineExecutionSummaries[0].pipelineExecutionId' --output text) \
    --query 'pipelineExecution.status' --output text

The build installs Rust in CodePipeline in your account and compiles the Cedar CLI. After approximately four minutes, the pipeline run status shows Succeeded.

Refactor some policies

This photo sharing application sample includes overlapping policies to simulate a refactoring workflow, where after changes are made, the test suite continues to pass. The DoePhotos.cedar and JaneVacation.cedar static policies are replaced by the logically equivalent viewPhoto.template.cedar policy template and two template-linked policies defined in cedartemplatelinks.json. After you delete the extra policies, the passing tests illustrate a successful refactor with the same expected application permissions.

To refactor policies

  1. Delete DoePhotos.cedar and JaneVacation.cedar.
  2. Commit the change to the repository.
    git add .
    git commit -m "Refactor some policies"
    git push codecommit main

  3. Check the pipeline progress. After about 20 seconds, the pipeline status shows Succeeded.

The second pipeline build runs quicker because the build specification is configured to cache a version of the Cedar CLI. Note that caching isn’t implemented in the local testing described in Option 2 of the local environment setup.

Break the build

After you confirm that you have a working pipeline that validates the Cedar policies, see what happens when you commit an invalid Cedar policy.

To break the build

  1. Using a text editor, open the file policystore/Photo-labels-private.cedar.
  2. In the when clause, change resource.labels to resource.label (removing the “s”). This policy syntax is valid, but no longer validates against the Cedar schema.
  3. Commit the change to the repository.
    git add .
    git commit -m "Break the build"
    git push codecommit main

  4. Sign in to the AWS Management Console and open the CodePipeline console.
  5. Wait for the Most recent execution field to show Failed.
  6. Select the pipeline and choose View in CodeBuild.
  7. Choose the Reports tab, and then choose the most recent report.
  8. Review the report summary, which shows details such as the total number of Passed and Failed/Error test case totals, and the pass rate, as shown in Figure 2.
  9. Figure 2: CodeBuild test report summary

    Figure 2: CodeBuild test report summary

  10. To get the error details, in the Details section, select the Test case called validate Photo-labels-private.cedar that has a Status of Error.
  11. Figure 3: CodeBuild test report test cases

    Figure 3: CodeBuild test report test cases

    That single policy change resulted in two test cases that didn’t pass. The detailed error message shown in Figure 4 is the output from the Cedar CLI. When the policy was validated against the schema, Cedar found the invalid attribute label on the entity type PhotoApp::Photo. The Failed message of unexpected ALLOW occurred because the label attribute typo prevented the forbid policy from matching and producing a DENY result. Each of these tests helps you avoid deploying invalid policies.

    Figure 4: CodeBuild test case error message

    Figure 4: CodeBuild test case error message

Clean up

To avoid ongoing costs and to clean up the resources that you deployed in your AWS account, complete the following steps:

To clean up the resources

  1. Open the Amazon S3 console, select the bucket that begins with the phrase cedar-policy-validation-codepipelinebucket, and Empty the bucket.
  2. Open the CloudFormation console, select the cedar-policy-validation stack, and then choose Delete.
  3. Open the CodeBuild console, choose Build History, filter by cedar-policy-validation, select all results, and then choose Delete builds.

Conclusion

In this post, you learned how to use AWS developer tools to implement a pipeline that automatically validates and tests when Cedar policies are updated and committed to a source code repository. Using this approach, you can detect invalid policies and potential application permission errors earlier in the development lifecycle and before deployment.

To learn more about the Cedar policy language, see the Cedar Policy Language Reference Guide or browse the source code at the cedar-policy organization on GitHub. For real-time validation of Cedar policies and schemas, install the Cedar policy language for Visual Studio Code extension.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the Amazon Verified Permissions re:Post or contact AWS Support.

Pontus Palmenas

Pontus Palmenäs

Pontus is a Startup Solutions Architect based in Stockholm, Sweden, where he is helping customers in healthcare and life sciences and FinTech. He is passionate about all things security. Outside of work, he enjoys making electronic music in his home studio and spending quality time with his family.

Kevin Hakanson

Kevin Hakanson

Kevin is a Senior Solutions Architect for AWS World Wide Public Sector based in Minnesota. He works with EdTech and GovTech customers to ideate, design, validate, and launch products using cloud-native technologies and modern development practices. When not staring at a computer screen, he is probably staring at another screen, either watching TV or playing video games with his family.

Building a generative AI Marketing Portal on AWS

Post Syndicated from Tristan Nguyen original https://aws.amazon.com/blogs/messaging-and-targeting/building-a-generative-ai-marketing-portal-on-aws/

Introduction

In the preceding entries of this series, we examined the transformative impact of Generative AI on marketing strategies in “Building Generative AI into Marketing Strategies: A Primer” and delved into the intricacies of Prompt Engineering to enhance the creation of marketing content with services such as Amazon Bedrock in “From Prompt Engineering to Auto Prompt Optimisation”. We also explored the potential of Large Language Models (LLMs) to refine prompts for more effective customer engagement.

Continuing this exploration, we will articulate how Amazon Bedrock, Amazon Personalize, and Amazon Pinpoint can be leveraged to construct a marketer portal that not only facilitates AI-driven content generation but also personalizes and distributes this content effectively. The aim is to provide a clear blueprint for deploying a system that crafts, personalizes, and distributes marketing content efficiently. This blog will guide you through the deployment process, underlining the real-world utility of these services in optimizing marketing workflows. Through use cases and a code demonstration, we’ll see these technologies in action, offering a hands-on perspective on enhancing your marketing pipeline with AI-driven solutions.

The Challenge with Content Generation in Marketing

Many companies struggle to streamline their marketing operations effectively, facing hurdles at various stages of the marketing operations pipeline. Below, we list the challenges at three main stages of the pipeline: content generation, content personalization, and content distribution.

Content Generation

Creating high-quality, engaging content is often easier said than done. Companies need to invest in skilled copywriters or content creators who understand not just the product but also the target audience. Even with the right talent, the process can be time-consuming and costly. Moreover, generating content at scale while maintaining quality and compliance to industry regulations is the key blocker for many companies considering adopting generative AI technologies in production environments.

Content Personalization

Once the content is created, the next hurdle is personalization. In today’s digital age, generic content rarely captures attention. Customers expect content tailored to their needs, preferences, and behaviors. However, personalizing content is not straightforward. It requires a deep understanding of customer data, which often resides in siloed databases, making it difficult to create a 360-degree view of the customer.

Content Distribution

Finally, even the most captivating, personalized content is ineffective if it doesn’t reach the right audience at the right time. Companies often grapple with choosing the appropriate channels for content distribution, be it email, social media, or mobile notifications. Additionally, ensuring that the content complies with various regulations and doesn’t end up in spam folders adds another layer of complexity to the distribution phase. Sending at scale requires paying attention to deliverability, security and reliability which often poses significant challenges to marketers.

By addressing these challenges, companies can significantly improve their marketing operations and empower their marketers to be more effective. But how can this be achieved efficiently and at scale? The answer lies in leveraging the power of Amazon Bedrock, Amazon Personalize, and Amazon Pinpoint, as we will explore in the following solution.

The Solution In Action

Before we dive into the details of the implementation, let’s take a look at the end result through the linked demo video.

Use Case 1: Banking/Financial Services Industry

You are a relationship manager working in the Consumer Banking department of a fictitious company called AnyCompany Bank. You are assigned a group of customers and would like to send out personalized and targeted communications to the channel of choice to every members of this group of customer.

Behind the scene, the marketer is utilizing Amazon Pinpoint to create the segment of customers they would like to target. The customers’ information and the marketer’s prompt are then fed into Amazon Bedrock to generate the marketing content, which is then sent to the customer via SMS and email using Amazon Pinpoint.

  • In the Prompt Iterator page, you can employ a process called “prompt engineering” to further optimize your prompt to maximize the effectiveness of your marketing campaigns. Please refer to this blog on the process behind engineering the prompt as well as how to apply an additional LLM model for auto-prompting. To get started, simply copy the sample banking prompt which has gone through the prompt engineering process in this page.
  • Next, you can either upload your customer group by uploading a .csv file (through “Importing a Segment”) or specify a customer group using pre-defined filter criteria based on your current customer database using Amazon Pinpoint.

UseCase1Segment

E.g.: The screenshot shows a sample filtered segment named ManagementOrRetired that only filters to customers who are management or retirees.

  • Once done, you can log into the marketer portal and choose the relevant segment that you’ve just created within the Amazon Pinpoint console.

PinpointSegment

  • You can then preview the customers and their information stored in your Amazon Pinpoint’s customer database. Once satisfied, we’re ready to start generating content for those customers!
  • Click on 1:1 Content Generator tab, your content is automatically generated for your first customer. Here, you can cycle through your customers one by one, and depending on the customer’s preferred language and channel, an email or SMS in the preferred language is automatically generated for them.
    • Generated SMS in English

PostiveSMS

    • A negative example showing proper prompt-engineering at work to moderate content. This happens if we try to insert data that does not make sense for the marketing content generator to output. In this case, the marketing generator refuses to output (justifiably) an advertisement for a 6-year-old on a secured instalment loan.

NegativeSMS

  • Finally, we choose to send the generated content via Amazon Pinpoint by clicking on “Send with Amazon Pinpoint”. In the back end, Amazon Pinpoint will orchestrate the sending of the email/SMS through the appropriate channels.
    • Alternatively, if the auto-generated content still did not meet your needs and you want to generate another draft, you can Disagree and try again.

Use Case 2: Travel & Hospitality

You are a marketing executive that’s working for an online air ticketing agency. You’ve been tasked to promote a specific flight from Singapore to Hong Kong for AnyCompany airline. You’d first like to identify which customers would be prime candidates to promote this flight leg to and then send out hyper-personalized message to them.

Behind the scene, instead of using Amazon Pinpoint to manually define the segment, the marketer in this case is leveraging AIML capabilities of Amazon Personalize to define the best group of customers to recommend the specific flight leg to them. Similar to the above use case, the customers’ information and LLM prompt are fed into the Amazon Bedrock, which generates the marketing content that is eventually sent out via Amazon Pinpoint.

  • Similar to the above use case, you’d need to go through a prompt engineering process to ensure that the content the LLM model is generating will be relevant and safe for use. To get started quickly, go to the Prompt Iterator page, you can use the sample airlines prompt and iterate from there.
  • Your company offers many different flight legs, aggregated from many different carriers. You first filter down to the flight leg that you want to promote using the Filters on the left. In this case, we are filtering for flights originating from Singapore (SRCCity) and going to Hong Kong (DSTCity), operated by AnyCompany Airlines.

PersonalizeInstructions

  • Now, let’s choose the number of customers that you’d like to generate. Once satisfied, you choose to start the batch segmentation job.
  • In the background, Amazon Personalize generates a group of customers that are most likely to be interested in this flight leg based on past interactions with similar flight itineraries.
  • Once the segmentation job is finished as shown, you can fetch the recommended group of customers and start generating content for them immediately, similar to the first use case.

Setup instructions

The setup instructions and deployment details can be found in the GitHub link.

Conclusion

In this blog, we’ve explored the transformative potential of integrating Amazon Bedrock, Amazon Personalize, and Amazon Pinpoint to address the common challenges in marketing operations. By automating the content generation with Amazon Bedrock, personalizing at scale with Amazon Personalize, and ensuring precise content distribution with Amazon Pinpoint, companies can not only streamline their marketing processes but also elevate the customer experience.

The benefits are clear: time-saving through automation, increased operational efficiency, and enhanced customer satisfaction through personalized engagement. This integrated solution empowers marketers to focus on strategy and creativity, leaving the heavy lifting to AWS’s robust AI and ML services.

For those ready to take the next step, we’ve provided a comprehensive guide and resources to implement this solution. By following the setup instructions and leveraging the provided prompts as a starting point, you can deploy this solution and begin customizing the marketer portal to your business’ needs.

Call to Action

Don’t let the challenges of content generation, personalization, and distribution hold back your marketing potential. Deploy the Generative AI Marketer Portal today, adapt it to your specific needs, and watch as your marketing operations transform. For a hands-on start and to see this solution in action, visit the GitHub repository for detailed setup instructions.

Have a question? Share your experiences or leave your questions in the comment section.

About the Authors

Tristan (Tri) Nguyen

Tristan (Tri) Nguyen

Tristan (Tri) Nguyen is an Amazon Pinpoint and Amazon Simple Email Service Specialist Solutions Architect at AWS. At work, he specializes in technical implementation of communications services in enterprise systems and architecture/solutions design. In his spare time, he enjoys chess, rock climbing, hiking and triathlon.

Philipp Kaindl

Philipp Kaindl

Philipp Kaindl is a Senior Artificial Intelligence and Machine Learning Solutions Architect at AWS. With a background in data science and
mechanical engineering his focus is on empowering customers to create lasting business impact with the help of AI. Outside of work, Philipp enjoys tinkering with 3D printers, sailing and hiking.

Bruno Giorgini

Bruno Giorgini

Bruno Giorgini is a Senior Solutions Architect specializing in Pinpoint and SES. With over two decades of experience in the IT industry, Bruno has been dedicated to assisting customers of all sizes in achieving their objectives. When he is not crafting innovative solutions for clients, Bruno enjoys spending quality time with his wife and son, exploring the scenic hiking trails around the SF Bay Area.

Architectural patterns for real-time analytics using Amazon Kinesis Data Streams, part 1

Post Syndicated from Raghavarao Sodabathina original https://aws.amazon.com/blogs/big-data/architectural-patterns-for-real-time-analytics-using-amazon-kinesis-data-streams-part-1/

We’re living in the age of real-time data and insights, driven by low-latency data streaming applications. Today, everyone expects a personalized experience in any application, and organizations are constantly innovating to increase their speed of business operation and decision making. The volume of time-sensitive data produced is increasing rapidly, with different formats of data being introduced across new businesses and customer use cases. Therefore, it is critical for organizations to embrace a low-latency, scalable, and reliable data streaming infrastructure to deliver real-time business applications and better customer experiences.

This is the first post to a blog series that offers common architectural patterns in building real-time data streaming infrastructures using Kinesis Data Streams for a wide range of use cases. It aims to provide a framework to create low-latency streaming applications on the AWS Cloud using Amazon Kinesis Data Streams and AWS purpose-built data analytics services.

In this post, we will review the common architectural patterns of two use cases: Time Series Data Analysis and Event Driven Microservices. In the subsequent post in our series, we will explore the architectural patterns in building streaming pipelines for real-time BI dashboards, contact center agent, ledger data, personalized real-time recommendation, log analytics, IoT data, Change Data Capture, and real-time marketing data. All these architecture patterns are integrated with Amazon Kinesis Data Streams.

Real-time streaming with Kinesis Data Streams

Amazon Kinesis Data Streams is a cloud-native, serverless streaming data service that makes it easy to capture, process, and store real-time data at any scale. With Kinesis Data Streams, you can collect and process hundreds of gigabytes of data per second from hundreds of thousands of sources, allowing you to easily write applications that process information in real-time. The collected data is available in milliseconds to allow real-time analytics use cases, such as real-time dashboards, real-time anomaly detection, and dynamic pricing. By default, the data within the Kinesis Data Stream is stored for 24 hours with an option to increase the data retention to 365 days. If customers want to process the same data in real-time with multiple applications, then they can use the Enhanced Fan-Out (EFO) feature. Prior to this feature, every application consuming data from the stream shared the 2MB/second/shard output. By configuring stream consumers to use enhanced fan-out, each data consumer receives dedicated 2MB/second pipe of read throughput per shard to further reduce the latency in data retrieval.

For high availability and durability, Kinesis Data Streams achieves high durability by synchronously replicating the streamed data across three Availability Zones in an AWS Region and gives you the option to retain data for up to 365 days. For security, Kinesis Data Streams provide server-side encryption so you can meet strict data management requirements by encrypting your data at rest and Amazon Virtual Private Cloud (VPC) interface endpoints to keep traffic between your Amazon VPC and Kinesis Data Streams private.

Kinesis Data Streams has native integrations with other AWS services such as AWS Glue and Amazon EventBridge to build real-time streaming applications on AWS. Refer to Amazon Kinesis Data Streams integrations for additional details.

Modern data streaming architecture with Kinesis Data Streams

A modern streaming data architecture with Kinesis Data Streams can be designed as a stack of five logical layers; each layer is composed of multiple purpose-built components that address specific requirements, as illustrated in the following diagram:

The architecture consists of the following key components:

  • Streaming sources – Your source of streaming data includes data sources like clickstream data, sensors, social media, Internet of Things (IoT) devices, log files generated by using your web and mobile applications, and mobile devices that generate semi-structured and unstructured data as continuous streams at high velocity.
  • Stream ingestion – The stream ingestion layer is responsible for ingesting data into the stream storage layer. It provides the ability to collect data from tens of thousands of data sources and ingest in real time. You can use the Kinesis SDK for ingesting streaming data through APIs, the Kinesis Producer Library for building high-performance and long-running streaming producers, or a Kinesis agent for collecting a set of files and ingesting them into Kinesis Data Streams. In addition, you can use many pre-build integrations such as AWS Database Migration Service (AWS DMS), Amazon DynamoDB, and AWS IoT Core to ingest data in a no-code fashion. You can also ingest data from third-party platforms such as Apache Spark and Apache Kafka Connect
  • Stream storage – Kinesis Data Streams offer two modes to support the data throughput: On-Demand and Provisioned. On-Demand mode, now the default choice, can elastically scale to absorb variable throughputs, so that customers do not need to worry about capacity management and pay by data throughput. The On-Demand mode automatically scales up 2x the stream capacity over its historic maximum data ingestion to provide sufficient capacity for unexpected spikes in data ingestion. Alternatively, customers who want granular control over stream resources can use the Provisioned mode and proactively scale up and down the number of Shards to meet their throughput requirements. Additionally, Kinesis Data Streams can store streaming data up to 24 hours by default, but can extend to 7 days or 365 days depending upon use cases. Multiple applications can consume the same stream.
  • Stream processing – The stream processing layer is responsible for transforming data into a consumable state through data validation, cleanup, normalization, transformation, and enrichment. The streaming records are read in the order they are produced, allowing for real-time analytics, building event-driven applications or streaming ETL (extract, transform, and load). You can use Amazon Managed Service for Apache Flink for complex stream data processing, AWS Lambda for stateless stream data processing, and AWS Glue & Amazon EMR for near-real-time compute. You can also build customized consumer applications with Kinesis Consumer Library, which will take care of many complex tasks associated with distributed computing.
  • Destination – The destination layer is like a purpose-built destination depending on your use case. You can stream data directly to Amazon Redshift for data warehousing and Amazon EventBridge for building event-driven applications. You can also use Amazon Kinesis Data Firehose for streaming integration where you can light stream processing with AWS Lambda, and then deliver processed streaming into destinations like Amazon S3 data lake, OpenSearch Service for operational analytics, a Redshift data warehouse, No-SQL databases like Amazon DynamoDB, and relational databases like Amazon RDS to consume real-time streams into business applications. The destination can be an event-driven application for real-time dashboards, automatic decisions based on processed streaming data, real-time altering, and more.

Real-time analytics architecture for time series

Time series data is a sequence of data points recorded over a time interval for measuring events that change over time. Examples are stock prices over time, webpage clickstreams, and device logs over time. Customers can use time series data to monitor changes over time, so that they can detect anomalies, identify patterns, and analyze how certain variables are influenced over time. Time series data is typically generated from multiple sources in high volumes, and it needs to be cost-effectively collected in near real time.

Typically, there are three primary goals that customers want to achieve in processing time-series data:

  • Gain insights real-time into system performance and detect anomalies
  • Understand end-user behavior to track trends and query/build visualizations from these insights
  • Have a durable storage solution to ingest and store both archival and frequently accessed data.

With Kinesis Data Streams, customers can continuously capture terabytes of time series data from thousands of sources for cleaning, enrichment, storage, analysis, and visualization.

The following architecture pattern illustrates how real time analytics can be achieved for Time Series data with Kinesis Data Streams:

Build a serverless streaming data pipeline for time series data

The workflow steps are as follows:

  1. Data Ingestion & Storage – Kinesis Data Streams can continuously capture and store terabytes of data from thousands of sources.
  2. Stream Processing – An application created with Amazon Managed Service for Apache Flink can read the records from the data stream to detect and clean any errors in the time series data and enrich the data with specific metadata to optimize operational analytics. Using a data stream in the middle provides the advantage of using the time series data in other processes and solutions at the same time. A Lambda function is then invoked with these events, and can perform time series calculations in memory.
  3. Destinations – After cleaning and enrichment, the processed time series data can be streamed to Amazon Timestream database for real-time dashboarding and analysis, or stored in databases such as DynamoDB for end-user query. The raw data can be streamed to Amazon S3 for archiving.
  4. Visualization & Gain insights – Customers can query, visualize, and create alerts using Amazon Managed Service for Grafana. Grafana supports data sources that are storage backends for time series data. To access your data from Timestream, you need to install the Timestream plugin for Grafana. End-users can query data from the DynamoDB table with Amazon API Gateway acting as a proxy.

Refer to Near Real-Time Processing with Amazon Kinesis, Amazon Timestream, and Grafana showcasing a serverless streaming pipeline to process and store device telemetry IoT data into a time series optimized data store such as Amazon Timestream.

Enriching & replaying data in real time for event-sourcing microservices

Microservices are an architectural and organizational approach to software development where software is composed of small independent services that communicate over well-defined APIs. When building event-driven microservices, customers want to achieve 1. high scalability to handle the volume of incoming events and 2. reliability of event processing and maintain system functionality in the face of failures.

Customers utilize microservice architecture patterns to accelerate innovation and time-to-market for new features, because it makes applications easier to scale and faster to develop. However, it is challenging to enrich and replay the data in a network call to another microservice because it can impact the reliability of the application and make it difficult to debug and trace errors. To solve this problem, event-sourcing is an effective design pattern that centralizes historic records of all state changes for enrichment and replay, and decouples read from write workloads. Customers can use Kinesis Data Streams as the centralized event store for event-sourcing microservices, because KDS can 1/ handle gigabytes of data throughput per second per stream and stream the data in milliseconds, to meet the requirement on high scalability and near real-time latency, 2/ integrate with Flink and S3 for data enrichment and achieving while being completely decoupled from the microservices, and 3/ allow retry and asynchronous read in a later time, because KDS retains the data record for a default of 24 hours, and optionally up to 365 days.

The following architectural pattern is a generic illustration of how Kinesis Data Streams can be used for Event-Sourcing Microservices:

The steps in the workflow are as follows:

  1. Data Ingestion and Storage – You can aggregate the input from your microservices to your Kinesis Data Streams for storage.
  2. Stream processing – Apache Flink Stateful Functions simplifies building distributed stateful event-driven applications. It can receive the events from an input Kinesis data stream and route the resulting stream to an output data stream. You can create a stateful functions cluster with Apache Flink based on your application business logic.
  3. State snapshot in Amazon S3 – You can store the state snapshot in Amazon S3 for tracking.
  4. Output streams – The output streams can be consumed through Lambda remote functions through HTTP/gRPC protocol through API Gateway.
  5. Lambda remote functions – Lambda functions can act as microservices for various application and business logic to serve business applications and mobile apps.

To learn how other customers built their event-based microservices with Kinesis Data Streams, refer to the following:

Key considerations and best practices

The following are considerations and best practices to keep in mind:

  • Data discovery should be your first step in building modern data streaming applications. You must define the business value and then identify your streaming data sources and user personas to achieve the desired business outcomes.
  • Choose your streaming data ingestion tool based on your steaming data source. For example, you can use the Kinesis SDK for ingesting streaming data through APIs, the Kinesis Producer Library for building high-performance and long-running streaming producers, a Kinesis agent for collecting a set of files and ingesting them into Kinesis Data Streams, AWS DMS for CDC streaming use cases, and AWS IoT Core for ingesting IoT device data into Kinesis Data Streams. You can ingest streaming data directly into Amazon Redshift to build low-latency streaming applications. You can also use third-party libraries like Apache Spark and Apache Kafka to ingest streaming data into Kinesis Data Streams.
  • You need to choose your streaming data processing services based on your specific use case and business requirements. For example, you can use Amazon Kinesis Managed Service for Apache Flink for advanced streaming use cases with multiple streaming destinations and complex stateful stream processing or if you want to monitor business metrics in real time (such as every hour). Lambda is good for event-based and stateless processing. You can use Amazon EMR for streaming data processing to use your favorite open source big data frameworks. AWS Glue is good for near-real-time streaming data processing for use cases such as streaming ETL.
  • Kinesis Data Streams on-demand mode charges by usage and automatically scales up resource capacity, so it’s good for spiky streaming workloads and hands-free maintenance. Provisioned mode charges by capacity and requires proactive capacity management, so it’s good for predictable streaming workloads.
  • You can use the Kinesis Shared Calculator to calculate the number of shards needed for provisioned mode. You don’t need to be concerned about shards with on-demand mode.
  • When granting permissions, you decide who is getting what permissions to which Kinesis Data Streams resources. You enable specific actions that you want to allow on those resources. Therefore, you should grant only the permissions that are required to perform a task. You can also encrypt the data at rest by using a KMS customer managed key (CMK).
  • You can update the retention period via the Kinesis Data Streams console or by using the IncreaseStreamRetentionPeriod and the DecreaseStreamRetentionPeriod operations based on your specific use cases.
  • Kinesis Data Streams supports resharding. The recommended API for this function is UpdateShardCount, which allows you to modify the number of shards in your stream to adapt to changes in the rate of data flow through the stream. The resharding APIs (Split and Merge) are typically used to handle hot shards.

Conclusion

This post demonstrated various architectural patterns for building low-latency streaming applications with Kinesis Data Streams. You can build your own low-latency steaming applications with Kinesis Data Streams using the information in this post.

For detailed architectural patterns, refer to the following resources:

If you want to build a data vision and strategy, check out the AWS Data-Driven Everything (D2E) program.


About the Authors

Raghavarao Sodabathina is a Principal Solutions Architect at AWS, focusing on Data Analytics, AI/ML, and cloud security. He engages with customers to create innovative solutions that address customer business problems and to accelerate the adoption of AWS services. In his spare time, Raghavarao enjoys spending time with his family, reading books, and watching movies.

Hang Zuo is a Senior Product Manager on the Amazon Kinesis Data Streams team at Amazon Web Services. He is passionate about developing intuitive product experiences that solve complex customer problems and enable customers to achieve their business goals.

Shwetha Radhakrishnan is a Solutions Architect for AWS with a focus in Data Analytics. She has been building solutions that drive cloud adoption and help organizations make data-driven decisions within the public sector. Outside of work, she loves dancing, spending time with friends and family, and traveling.

Brittany Ly is a Solutions Architect at AWS. She is focused on helping enterprise customers with their cloud adoption and modernization journey and has an interest in the security and analytics field. Outside of work, she loves to spend time with her dog and play pickleball.