Tag Archives: Advanced (300)

Amazon Managed Service for Apache Flink application lifecycle management with Terraform 

Post Syndicated from Felix John original https://aws.amazon.com/blogs/big-data/amazon-managed-service-for-apache-flink-application-lifecycle-management-with-terraform/

In this post, you’ll learn how to use Terraform to automate and streamline your Apache Flink application lifecycle management on Amazon Managed Service for Apache Flink. We’ll walk you through the complete lifecycle including deployment, updates, scaling, and troubleshooting common issues.

Managing Apache Flink applications through their entire lifecycle from initial deployment to scaling or updating can be complex and error-prone when done manually. Teams often struggle with inconsistent deployments across environments, difficulty tracking configuration changes over time, and complex rollback procedures when issues arise.

Infrastructure as Code (IaC) addresses these challenges by treating infrastructure configuration as code that can be versioned, tested, and automated. While there are different IaC tools available including AWS CloudFormation or AWS Cloud Development Kit (AWS CDK), we focus on HashiCorp Terraform to automate the complete lifecycle management of Apache Flink applications on Amazon Managed Service for Apache Flink.

Managed Service for Apache Flink allows you to run Apache Flink jobs at scale without worrying about managing clusters and provisioning resources. You can focus on developing your Apache Flink using your Integrated Development Environment (IDE) of choice, building and packaging the application using standard build and CI/CD tools. Once your application is packaged and uploaded to Amazon S3, you can deploy and run it with a serverless experience.

While you can control your Managed Service for Apache Flink applications directly using the AWS Console, CLI, or SDKs, Terraform provides key advantages such as version control of your application configuration, consistency across environments, and seamless CI/CD integration. This post builds upon our two-part blog series “Deep dive into the Amazon Managed Service for Apache Flink application lifecycle – Part 1” and “Part 2” that discusses the general lifecycle concepts of Apache Flink applications.

We use the sample code published on the GitHub repository to demonstrate the lifecycle management. Note that this is not a production-ready solution.

Setting up your Terraform environment

Before you can manage your Apache Flink applications with Terraform, you need to set up your execution environment. In this section, we’ll cover how to configure Terraform state management and credential handling. The Terraform AWS provider supports Managed Service for Apache Flink through the aws_kinesis_analyticsv2_application resource (using the legacy name “Kinesis Analytics V2“).

Terraform state management

Terraform uses a state file to track the resources it manages. In Terraform, storing the state file in Amazon S3 is a best practice for teams working collaboratively because it provides a centralised, durable, and secure location for tracking infrastructure changes. However, since multiple engineers or CI/CD pipelines may run Terraform simultaneously, state locking is essential to prevent race conditions where concurrent executions could corrupt the state. S3 as backend is commonly used for state storage and locking, ensuring that only one Terraform process can modify the state at a time, thus maintaining infrastructure consistency and avoiding deployment conflicts.

Passing credentials

To run Terraform inside a Docker container while ensuring that it has access to the necessary AWS credentials and infrastructure code, we follow a structured approach. This process involves exporting AWS credentials, mounting required directories, and executing Terraform commands inside a Docker container. Let’s break this down step by step. Before running Terraform, we need to make sure that our Docker container has access to the required AWS credentials. Since we are using temporary credentials, we generate them using the AWS CLI with the following command:

aws configure export-credentials --profile $AWS_PROFILE --format env-no-export > .env.docker

This command does the following:

  • It exports AWS credentials from a specific AWS profile ($AWS_PROFILE).
  • The credentials are saved in .env.docker in a format suitable for Docker.
  • The --format env-no-export option displays credentials as non-exported shell variables

This file (.env.docker) will later be used to pass credentials into the Docker container

Running Terraform in Docker

Running Terraform inside a Docker container provides a consistent, portable, and isolated environment for managing infrastructure without requiring Terraform to be installed directly on the local machine. This approach ensures that Terraform runs in a controlled environment, reducing dependency conflicts and improving security. To execute Terraform within a Docker container, we use a docker run command that mounts the necessary directories and passes AWS credentials, allowing Terraform to apply infrastructure changes seamlessly.

The Terraform configuration files are stored in a local terraform folder, which is virtually attached to the container using the -v flag. This allows the containerised Terraform instance to access and modify infrastructure code as if it were running locally.

To run Terraform in Docker, the following command is executed:

docker run --env-file .env.docker --rm -it \
-v ./flink:/home/flink-project/flink \
-v ./terraform:/home/flink-project/terraform \
-v ./build.sh:/home/flink-project/build.sh \
msf-terraform bash build.sh apply

Breaking down this command step by step:

  • --env-file .env.docker provides the AWS credentials required for Terraform to authenticate.
  • --rm -it runs the container interactively and is removed after execution to prevent clutter.
  • -v ./terraform:/home/flink-project/terraform mounts the Terraform directory into the container, making the configuration files accessible.
  • -v ./build.sh:/home/flink-project/build.sh mounts the build.sh script, which contains the logic to build JAR file for flink and execute Terraform commands.
  • msf-terraform is the Docker image used, which has Terraform pre-installed.
  • bash build.sh apply runs the build.sh script inside the container, passing apply as an argument to trigger the Terraform apply process.

Inside the container, build.sh typically includes commands such as terraform init to initialise the Terraform working directory and terraform apply to apply infrastructure changes. Since the Terraform execution happens entirely within the container, there is no need to install Terraform locally, and the process remains consistent across different systems. This method is particularly beneficial for teams working in collaborative environments, as it standardises Terraform execution and allows for reproducibility across development, staging, and production environments.

Managing application lifecycle with Terraform

In this section, we walk through each phase of the Apache Flink application lifecycle and understand how you can implement these operations using Terraform. While these operations are usually fully automated as part of a CI/CD pipeline, you will execute the individual steps manually from the command line for demonstration purposes. There are many ways to run Terraform depending on your organization’s tooling and infrastructure setup, but for this demonstration, we run Terraform in a container alongside the application build to simplify dependency management. In real-world scenarios, you would typically have separate CI/CD stages for building your application and deploying with Terraform, with distinct configurations for each environment. Since every organization has different CI/CD tooling and approaches, we keep these implementation details out of scope and focus on the core Terraform operations.

For a comprehensive deep dive into Apache Flink application lifecycle operations, refer to our previous two-part blog series.

Create and start a new application

To get started you want to create your Apache Flink application running on Managed Service for Apache Flink. You should execute the following Docker command:

docker run --env-file .env.docker --rm -it \
-v ./flink:/home/flink-project/flink \
-v ./terraform:/home/flink-project/terraform \
-v ./build.sh:/home/flink-project/build.sh \
msf-terraform bash build.sh apply

This command will complete the following operations by executing the bash script build.sh:

  1. Building the Java ARchive (JAR) file from your Apache Flink application
  2. Uploading the JAR file to S3
  3. Setting the config variables for your Apache Flink application in terraform/config.tfvars.json
  4. Create and deploy the Apache Flink application to Managed Service for Apache Flink using terraform apply

Terraform fully covers this operation. You can check the running Apache Flink application using AWS CLI or inside the Managed Apache Flink Console after Terraform completes with Apply Complete! Terraform is expecting the Apache Flink artifact, i.e. the JAR file to be packaged and copied to S3. This operation is usually part of the CI/CD pipeline and executed before invoking the terraform apply. Here, the operation is specified in the build.sh script.

Deploy code change to an application

You have successfully created and started the Flink application. However, you realize that you have to make a change to the Flink application code. Let’s make a code change to the application code in flink/ and see how to build and deploy it. After making the necessary changes, you simply have to run the following Docker command again that builds the JAR file, uploads it to S3 and deploys the Apache Flink application using Terraform:

docker run --env-file .env.docker --rm -it \
-v ./flink:/home/flink-project/flink \
-v ./terraform:/home/flink-project/terraform \
-v ./build.sh:/home/flink-project/build.sh \
msf-terraform bash build.sh apply

This phase of the lifecycle is fully supported by Terraform as long as both applications are state compatible, meaning that the operators of the upgraded Apache Flink application are able to restore the state from the snapshot that is taken from the old application version, before Managed Service for Apache Flink stops and deploys the change. For example, removing a stateful operator without enabling the allowNonRestoredState flag or changing an operator’s UID could prevent the new application from restoring from the snapshot. For more information on state compatibility, refer to Upgrading Applications and Flink Versions. For an example of state incompatibility, and strategies for handling state incompatibility, refer to Introducing the new Amazon Kinesis source connector for Apache Flink.

When deploying a code change goes wrong – A problem prevents the application code from being deployed

You also need to be careful with deploying code changes that contain bugs preventing the Apache Flink job from starting. For more information, refer to failure mode (a) – a problem prevents the application code from being deployed under When starting or updating the application goes wrong. For instance, this can be simulated by setting the mainClass in flink/pom.xml mistakenly to com.amazonaws.services.msf.WrongJob. Similar to before you build the JAR, upload it and run the terraform apply by running the Docker command from above. However, Terraform now fails to correctly apply the changes and throws an error message as the Apache Flink application fails to correctly update. Finally, the application status moves to READY.

Error message from terminal

To remedy the issue, you have to change the value of mainClass back to the original one and deploy the changes to Managed Service for Apache Flink. The Apache Flink application remains in READY status and doesn’t start automatically, as this was its state before applying the fix. Note that Terraform does not try to start the application when you deploy a change. You will have to manually start the Flink application using the AWS CLI or through the Managed Apache Flink Console.

As detailed in Part 2 of the companion blog, there is a second failure scenario where the application starts successfully, but the job becomes stuck in a continuous fail-and-restart loop. A code change can also cause this failure mode. We will cover the second error scenario when we cover deploying configuration changes.

Manual rollback application code to previous application code

As part of the lifecycle management of your Apache Flink application, you may need to explicitly rollback to a previous running application version. This is particularly useful when a newly deployed application version with application code changes exhibits unexpected behaviour and you want to explicitly rollback the application. Currently, Terraform does not support explicit rollbacks of your Apache Flink application running in Managed Service for Apache Flink. You will have to resort to therollbackApplication API through the AWS CLI or the Managed Service for Apache Flink Console to revert the application to the previous running version.

When you perform the explicit rollback, Terraform will initially not be aware of the changes. More specifically, the S3 path to the JAR file in the Managed Service for Apache Flink service (see left part of the image below) is different to the S3 path denoted in the terraform.tfstate file stored in Amazon S3 (see the right part of the image below). Fortunately, Terraform will always perform refreshing actions that include reading the current settings from all managed remote objects and updating the Terraform state to match as part of creating a plan in both terraform plan and terraform apply commands.
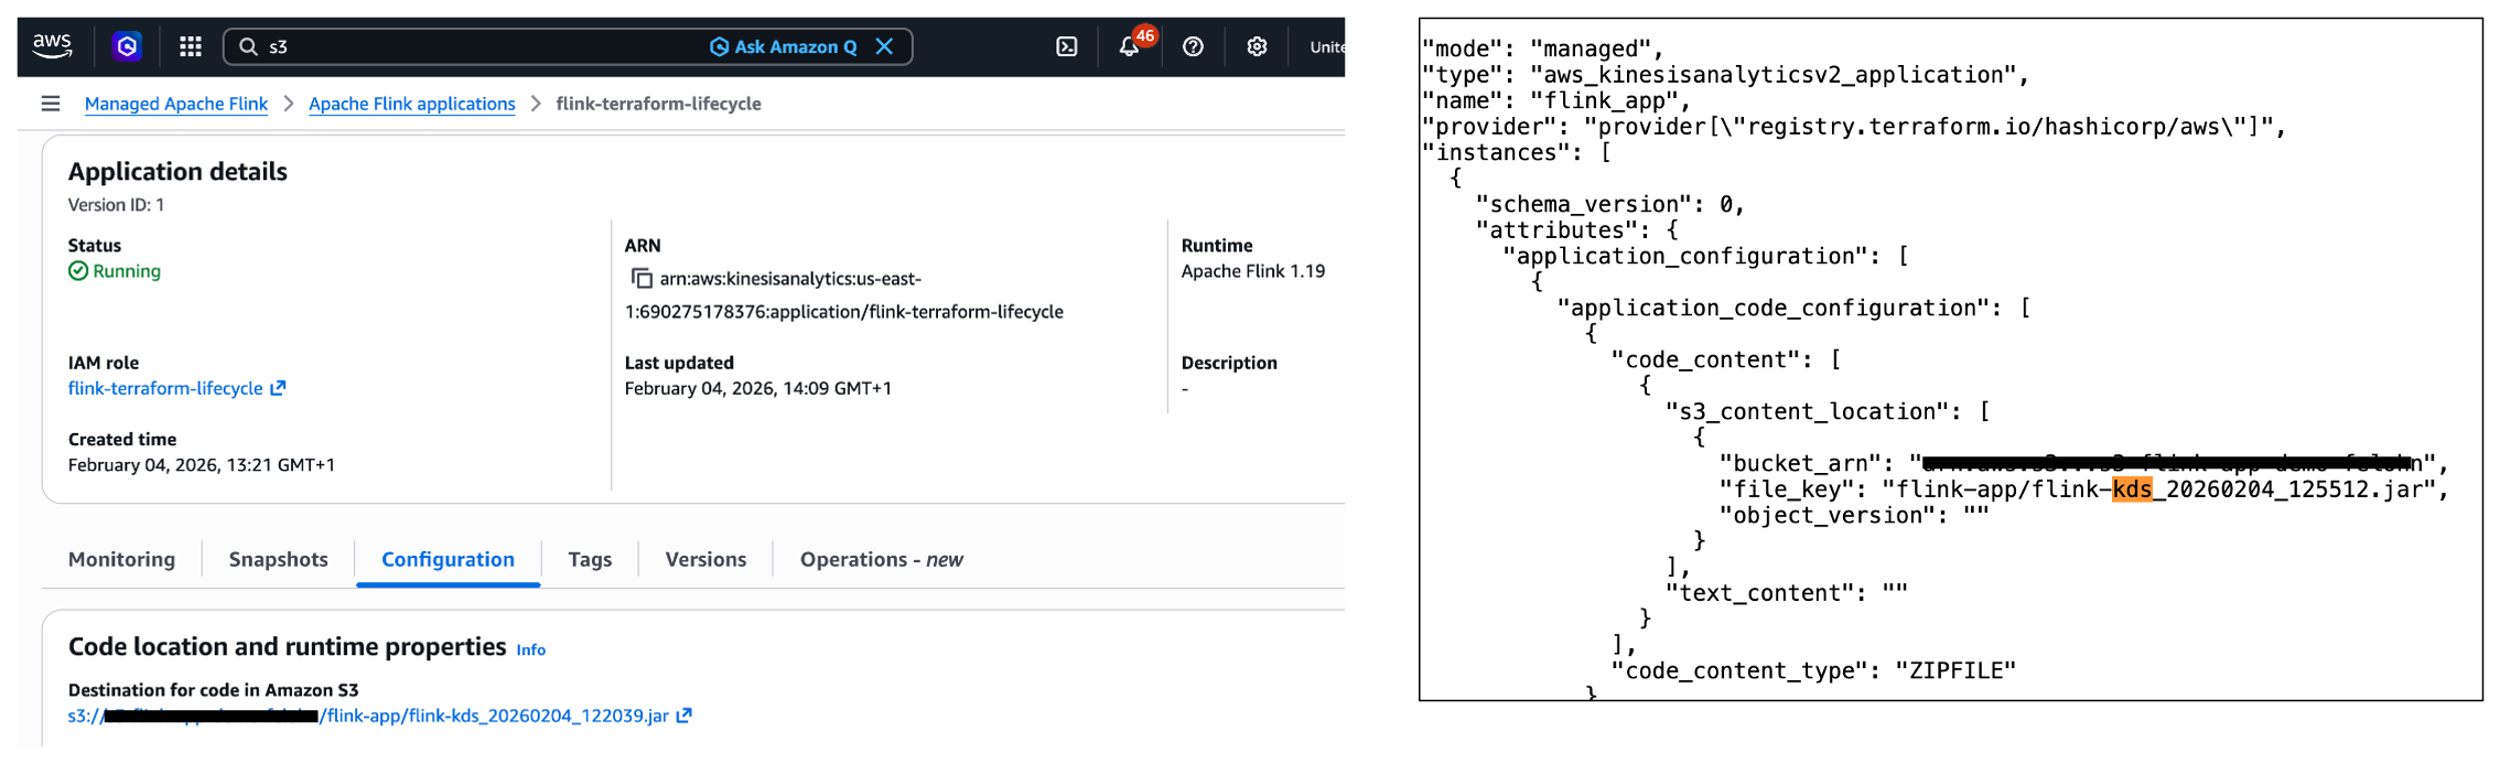
Terraform State vs. MSF State

In summary, while you can not perform a manual rollback using Terraform, Terraform will automatically refresh the state when deploying a change using terraform apply.

Deploy config change to application

You have already made changes to the application code of your Apache Flink application. What about making changes to the config of the application, e.g., changing runtime parameters? Imagine you want to change the application logging level of your running Apache Flink application. To change the logging level from ERROR to INFO, you have to change the value for flink_app_monitoring_metrics_level in the terraform/config.tfvars.json to INFO. To deploy the config changes, you need to run the docker run command again as done in the previous sections. This scenario works as expected and is fully covered by Terraform.

What happens when the Apache Flink application deploys successfully but fails and restarts during execution? For more information, please refer to failure mode (b) – the application is started, the job is stuck in a fail-and-restart loop under When starting or updating the application goes wrong. Note that this failure mode can happen when making code changes as well.

When deploying config change goes wrong – The application is started, the job is stuck in a fail-and-restart loop

In the following example, we apply a wrong configuration change preventing the Kinesis connector from initialising correctly, ultimately putting the job in a fail-and-restart loop. To simulate this failure scenario, you’ll need to modify the Kinesis stream configuration by changing the stream name to a non-existent one. This change is made in the terraform/config.tfvars.json file, specifically altering the stream.name value under flink_app_environment_variables. When you deploy with this invalid configuration, the initial deployment will appear successful, showing an Apply Complete! message. The Flink application status will also show as RUNNING. However, the actual behaviour reveals problems. If you check the Flink Dashboard, you’ll see the application is continuously failing and restarting. Also, you will see a warning message about the application requiring attention in the AWS Console.
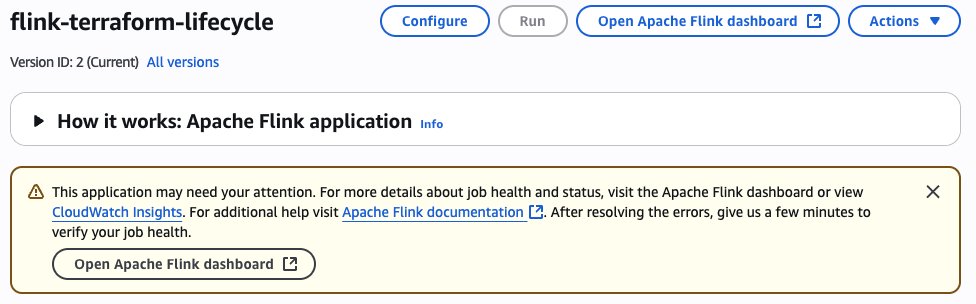
Problem message within the MSF Console

As detailed in the section Monitoring Apache Flink application operations in the companion blog (part 2), you can monitor the FullRestarts metric to detect the fail-and-restart loop.

Reverting the changes made to the environment variable and deploying the changes will result in Terraform showing the following error message: Failed to take snapshot for the application flink-terraform-lifecycle at this moment. The application is currently experiencing downtime.

Error message 2 from terminal

You have to force-stop without a snapshot and restart the application with a snapshot to get your Flink application back to a properly functioning state. You should constantly monitor the application state of your Apache Flink application to detect any issues.

Other common operations

Manually scaling the application

Another common operation in the lifecycle of your Apache Flink application is scaling the application up or down by adjusting the parallelism. This operation changes the number of Kinesis Processing Units (KPUs) allocated to your application. Let’s look at two different scaling scenarios and how they are handled by Terraform.

In the first scenario, you want to change the parallelism of your running Apache Flink application within the default parallelism quota. To do this, you need to modify the value for flink_app_parallelism in the terraform/config.tfvars.json file. After updating the parallelism value, you deploy the changes by running the Docker command as done in the previous sections:

docker run --env-file .env.docker --rm -it \
-v ./flink:/home/flink-project/flink \
-v ./terraform:/home/flink-project/terraform \
-v ./build.sh:/home/flink-project/build.sh \
msf-terraform bash build.sh apply

This scenario works as expected and is fully covered by Terraform. The application will be updated with the new parallelism setting, and Managed Service for Apache Flink will adjust the allocated KPUs accordingly. Note that there is a default quota of 64 KPUs for a single Managed Service for Apache Flink application, which must be raised proactively via a quota increase request if you need to scale your Managed Service for Apache Flink application beyond 64 KPUs. For more information, refer to Managed Service for Apache Flink quota.

Less common change deployments which require special handling In this section we analyze some less common change deployment scenarios which require some special handling.

Deploy code change that removes an operator

Removing an operator from your Apache Flink application requires special consideration, particularly regarding state management. When you remove an operator, the state from that operator still exists in the latest snapshot, but there’s no longer a corresponding operator to restore it. Let’s take a closer look at this scenario and understand how you can handle it properly. First, you need to make sure that the parameter AllowNonRestoredState is set to True. This parameter specifies whether the runtime is allowed to skip a state that cannot be mapped to the new program, when restoring from a snapshot. Allowing non-restored state is required to successfully update an Apache Flink application when you dropped an operator. To enable the AllowNonRestoredState, you need to set the configuration value for flink_app_allow_non_restored_state to true in terraform/config.tfvars.json. Then, you can go ahead and remove an operator: For example, you can directly have the sourceStream write to the sink connector in flink/src/main/java/com/amazonaws/services/msf/StreamingJob.java. Change code line 146 from windowedStream.sinkTo(sink).uid("kinesis-sink")to sourceStream.sinkTo(sink).uid("kinesis-sink"). Make sure that you have commented out the entire windowedStream code block (lines 103 to 140).

This change will remove the windowed computation and directly connect the source stream to the sink, effectively removing the stateful operation. After removing the operator from your Flink application code, you deploy the changes using the Docker command as previously done. However, the deployment fails with the following error message: Could not execute application. As a result, the Apache Flink application moves to the READY state. To recover from this situation, you need to restart the Apache Flink application using the latest snapshot for the application to successfully start and move to RUNNING status. Importantly, you need to make sure that AllowNonRestoredState is enabled. Otherwise, the application will fail to start as it cannot restore the state for the removed operator.

Deploy change that breaks state compatibility with system rollback enabled

During the lifecycle management of your Apache Flink application, you might encounter scenarios where code changes break state compatibility. This typically happens when you modify stateful operators in ways that prevent them from restoring their state from previous snapshots.

A common example of breaking state compatibility is changing the UID of a stateful operator (such as an aggregation or windowing operator) in your application code. To safeguard against such breaking changes, you can enable the automatic system rollback feature in Managed Service for Apache Flink as described in the subsection Rollback under Lifecycle of an application in Managed Service for Apache Flink previously. This feature is disabled by default and can be enabled using the AWS Management Console or invoking the UpdateApplication API operation. There is no way in Terraform to enable system rollback.

Next, let’s demonstrate this by breaking the state compatibility of your Apache Flink application by changing the UID of a stateful operator, e.g., the string windowed-avg-price in line 140 of flink/src/main/java/com/amazonaws/services/msf/StreamingJob.java to windowed-avg-price-v2 and deploy the changes as before. You will encounter the following error:

Error: waiting for Kinesis Analytics v2 Application (flink-terraform-lifecycle) operation (*) success: unexpected state ‘FAILED’, wanted target ‘SUCCESSFUL’. last error: org.apache.flink.runtime.rest.handler.RestHandlerException: Could not execute application.

At this point, Managed Service for Apache Flink automatically rolls back the application to the previous snapshot with the previous JAR file, maintaining your application’s availability as you have enabled system-rollback capability. Terraform will initially be not aware of the performed rollback. Fortunately, as we have already witnessed in subsection Manual rollback application code to previous application code, Terraform will automatically refresh the state when we change UID to the previous value and deploy the changes.

In-place upgrade of Apache Flink runtime version

Managed Service for Apache Flink supports in-place upgrade to new Flink runtime versions. See the documentation for more details. Updating the application dependencies and any required code changes is a responsibility of the user. Once you have updated the code artifact, the service is able to upgrade the runtime of your running application in-place, without data loss. Let’s examine how Terraform handles Flink version upgrades.

To upgrade your Apache Flink application from version 1.19.1 to 1.20, you need to:

  1. Update the Flink dependencies in your flink/pom.xml to version 1.20.0 (flink.version to 1.20.1 and flink.connector.version to 5.0.0-1.20 in <properties>)
  2. Update the flink_app_runtime_environment to FLINK-1_20 in terraform/config.tfvars.json
  3. Build and deploy the changes using the familiar docker run command

Terraform successfully performs an in-place upgrade of your Flink application. You will receive the following message: Apply complete! Resources: 0 added, 1 changed, 0 destroyed.

Operations currently not supported by Terraform

Let’s take a closer look at operations that are currently not supported by Terraform.

Starting or stopping the application without any configuration change

Terraform provides the start_application parameter, indicating whether to start or stop the application. You can set this parameter using flink_app_start in config.tfvars.json to stop your running Apache Flink application. However, this will only work if the current configuration value is set to true. In other words, Terraform only responds to the change in the parameter value, not the absolute value itself. After Terraform applies this change, your Apache Flink application will stop and its application status will move to READY. Similarly, restarting the application requires changing the flink_app_start value back to true, but this will only take effect if the current configuration value is false. Terraform will then restart your application, moving it back to the RUNNING state.

In summary, you cannot start or stop your Apache Flink application without making any configuration change in Terraform. You have to use AWS CLI, AWS SDK or AWS Console to start or stop your application.

Restarting application from an older snapshot or no snapshot without any configuration change

Similar to the previous section, Terraform requires an actual configuration change of application_restore_type to trigger a restart with different snapshot settings. Simply reapplying the same configuration values won’t initiate a restart from a different snapshot or no snapshot. You have to use AWS CLI, AWS SDK or AWS Console to restart your application from an older snapshot.

Performing rollback triggered manually or by system-rollback feature

Terraform does not support performing a manual rollback nor automatic system rollback. In addition, Terraform will also not be aware when such a rollback is taking place. The state information will be outdated, e.g. S3 path information. However, Terraform automatically performs refreshing actions to read settings from all managed remote objects and updates the Terraform state to match. Consequently, you can have Terraform refresh the Terraform state by successfully running a terraform apply command.

Conclusion

In this post, we demonstrated how to use Terraform to automate the lifecycle management of your Apache Flink applications on Managed Service for Apache Flink. We walked through fundamental operations including creating, updating, and scaling applications, explored how Terraform handles various failure scenarios and examined advanced scenarios such as removing operators and performing in-place runtime upgrades. We also identified operations that are currently not supported by Terraform.

For more information, see Run a Managed Service for Apache Flink application and our two-part blog on Deep dive into the Amazon Managed Service for Apache Flink application lifecycle.

Felix John

Felix John

Felix is a Global Solutions Architect and data & AI expert at AWS, based out of Germany. He focuses on supporting AWS’ strategic global automotive & manufacturing customers on their cloud journey.

Mazrim Mehrtens

Mazrim Mehrtens

Mazrim is a Sr. Specialist Solutions Architect for messaging and streaming workloads. Mazrim works with customers to build and support systems that process and analyze terabytes of streaming data in real time, run enterprise Machine Learning pipelines, and create systems to share data across teams seamlessly with varying data toolsets and software stacks.

Build a data pipeline from Google Search Console to Amazon Redshift using AWS Glue

Post Syndicated from Anirudh Chawla original https://aws.amazon.com/blogs/big-data/build-a-data-pipeline-from-google-search-console-to-amazon-redshift-using-aws-glue/

Google Search Console (GSC) is a service offered by Google that helps you monitor, maintain, and troubleshoot your site’s presence in Google Search results. It provides you unique insights directly from Google about how the search engine sees your site, helping you improve your performance in Search Engine Results Pages (SERPs).

When there is a need to merge Google Search Console data with multiple data sources or conduct complex performance analysis, traditional methods can become time-consuming and error-prone. This is where Amazon Redshift and AWS Glue offer a comprehensive data integration solution.

In this post, we explore how AWS Glue extract, transform, and load (ETL) capabilities connect Google applications and Amazon Redshift, helping you unlock deeper insights and drive data-informed decisions through automated data pipeline management. We walk you through the process of using AWS Glue to integrate data from Google Search Console and write it to Amazon Redshift.

Solution overview

AWS Glue is a serverless data integration service that helps discover, prepare, and combine data for analytics, machine learning (ML), and application development. You can use AWS Glue to create, run, and monitor data integration and ETL pipelines and catalog your assets across multiple data stores.

Amazon Redshift is a fast, scalable, and fully managed cloud data warehouse that lets you to process and run complex SQL analytics workloads on structured and semi-structured data. It also helps you securely access your data in operational databases, data lakes, or third-party datasets with minimal movement or copying of data. Tens of thousands of customers use Amazon Redshift to process large amounts of data, modernize their data analytics workloads, and provide insights for their business users.

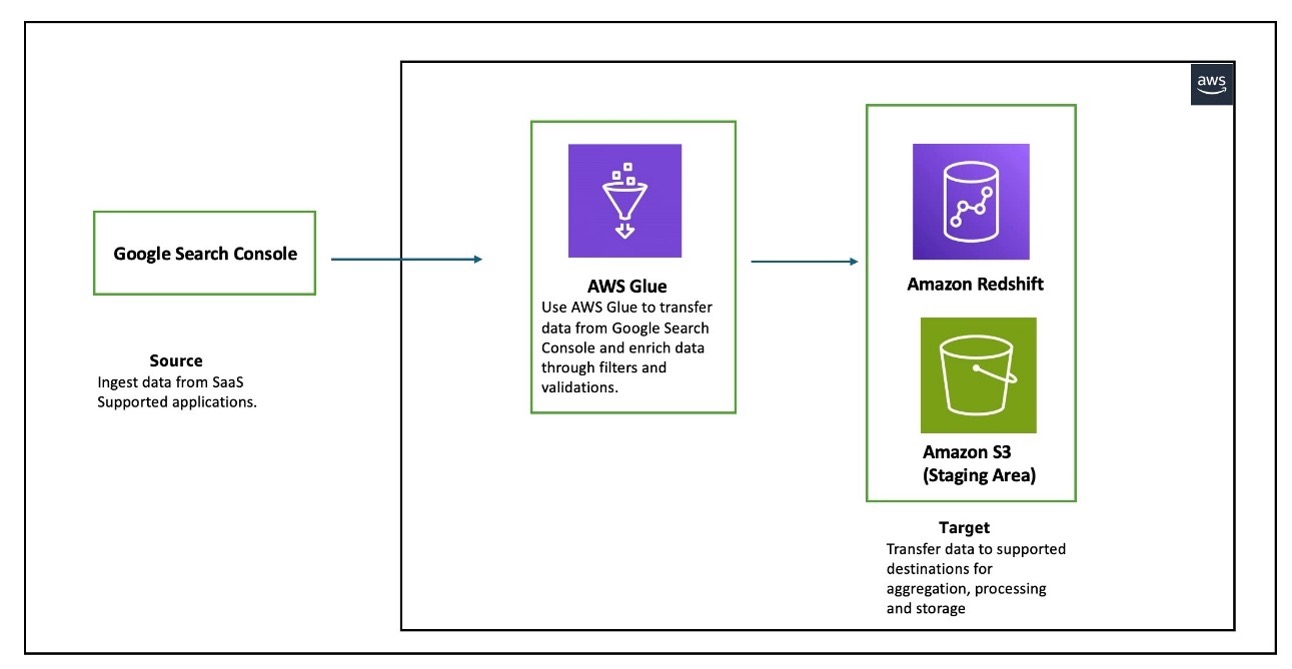
The following diagram illustrates the architecture that we implement in this post.

Architecture diagram showing AWS Glue data pipeline workflow from Google Search Console to Amazon Redshift, illustrating the ETL process with AWS Glue job reading data from three Google Search Console entities (Search Analytics, Sites, and Sitemaps) and writing to a Redshift provisioned cluster.

The workflow consists of an AWS Glue job reading data from Google Search Console for the three entities that Google Search Console supports (Search Analytics, Sites, and Sitemaps), and writing the data in a Redshift provisioned cluster. AWS Glue supports Google Search Console API v3.

In the following sections, we walk through the following steps to configure AWS Glue to set up a connection between Google Search Console and Amazon Redshift for data migration:

  1. Create an OAuth client.
  2. Create an IAM role for AWS Glue integration with Google Search Console, AWS Secrets Manager, and Amazon Redshift.
  3. Create a secret in Secrets Manager to store the client secret created in the previous step.
  4. Create a connection to Google Search Console in AWS Glue.
  5. Create a connection to Amazon Redshift in AWS Glue.
  6. Set up a table and permissions in Amazon Redshift.
  7. Create an ETL job in AWS Glue.

Prerequisites

Before starting this walkthrough, you must have the following prerequisites in place:

  • An AWS account.
  • A Google Cloud account and a Google Cloud project.
  • In your Google Cloud project, you must enable the Google Search Console API.
    For instructions, see Enable and disable APIs on the API Console Help for Google Cloud Platform.
  • A provisioned cluster or Amazon Redshift Serverless .
    In this post, we use a single-node ra3.large Redshift provisioned cluster deployed in a single Availability Zone. This configuration is used for demonstration purposes only. For production environments, we recommend using multi-node clusters with a minimum of two nodes deployed across multiple Availability Zones for high availability and better performance.
  • An Amazon Simple Service Storage (Amazon S3) bucket.
  • An AWS Identity and Access Management (IAM) role that grants AWS Glue and Amazon Redshift read-only access to Amazon S3. This role will be attached to the Redshift cluster or Redshift Serverless namespace during creation, and will also be used when running the AWS Glue job along with permissions to read and write secrets to Secrets Manager. Refer to the Amazon Redshift Database Developer Guide for more details.

Create OAuth client

To connect to Google Search Console, AWS Glue requires OAuth 2.0 for authentication. You must create an OAuth 2.0 client ID, which AWS Glue uses when requesting an OAuth 2.0 access token. To create an OAuth 2.0 client ID in the Google Cloud Platform console, follow these steps:

  1. On the Google Cloud Platform console, from the projects list, choose a project or create a new one.
  2. If the APIs & Services page isn’t already open, choose the menu icon on the upper left and choose APIs & Services.
  3. In the navigation pane, choose Credentials.
  4. Choose Create Credentials, then choose OAuth client ID.
  5. Select Web application as the application type, enter NewClient as the name, and provide https://console.aws.amazon.com for Authorized JavaScript origins.
  6. For Authorized redirect URIs, add https://us-east-1.console.aws.amazon.com/gluestudio/oauth. This example uses us-east-1 for setting up AWS Glue jobs; change the redirect URIs according to your AWS Region. Multiple redirect URIs can also be specified.
  7. Choose Create.
  8. Open the details page for your new client.
  9. Under Additional information, note down the client ID and client secret. You will need these details when configuring the secret in Secrets Manager.

Create IAM role for AWS Glue integration with Google Search Console, Secrets Manager, and Amazon Redshift

You can use AWS Glue to transfer data from supported sources into your Redshift databases. You need an IAM role because AWS Glue needs authorization to write into Redshift databases. To create a role, complete the following steps:

  1. Sign in to the IAM console with sufficient access to create policies.
  2. Choose Policies in the navigation pane.
  3. Choose Create policy.
  4. On the JSON tab, enter the following policy. AWS Glue needs the following permissions to access and run SQL statements in the Redshift database and create and retrieve secrets with Secrets Manager:
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Effect": "Allow",
                "Action": [
                    "secretsmanager:DescribeSecret",
                    "secretsmanager:GetSecretValue",
                    "secretsmanager:PutSecretValue",
                    "ec2:CreateNetworkInterface",
                    "ec2:DescribeNetworkInterfaces",
                    "ec2:DeleteNetworkInterface"
                ],
                "Resource": "*"
            },
            {
                "Effect": "Allow",
                "Action": "s3:GetObject",
                "Resource": "arn:aws:s3:::aws-glue-studio-transforms-510798373988-prod-us-east-1/*"
            },
            {
                "Effect": "Allow",
                "Action": [
                    "s3:GetObject",
                    "s3:PutObject"
                ],
                "Resource": [
                    "arn:aws:s3:::aws-glue-assets-testbucket/*"
                ]
            },
            {
                "Sid": "DataAPIPermissions",
                "Effect": "Allow",
                "Action": [
                    "redshift-data:ExecuteStatement",
                    "redshift-data:GetStatementResult",
                    "redshift-data:DescribeStatement"
                ],
                "Resource": "*"
            },
            {
                "Sid": "GetCredentialsForAPIUser",
                "Effect": "Allow",
                "Action": "redshift:GetClusterCredentials",
                "Resource": [
                    "arn:aws:redshift:*:*:dbname:*/*",
                    "arn:aws:redshift:*:*:dbuser:*/*"
                ]
            },
            {
                "Sid": "GetCredentialsForServerless",
                "Effect": "Allow",
                "Action": "redshift-serverless:GetCredentials",
                "Resource": "*"
            },
            {
                "Sid": "DenyCreateAPIUser",
                "Effect": "Deny",
                "Action": "redshift:CreateClusterUser",
                "Resource": [
                    "arn:aws:redshift:*:*:dbuser:*/*"
                ]
            },
            {
                "Sid": "ServiceLinkedRole",
                "Effect": "Allow",
                "Action": "iam:CreateServiceLinkedRole",
                "Resource": "arn:aws:iam::*:role/aws-service-role/redshift-data.amazonaws.com/AWSServiceRoleForRedshift",
                "Condition": {
                    "StringLike": {
                        "iam:AWSServiceName": "redshift-data.amazonaws.com"
                    }
                }
            }
        ]
    }

    Modify the S3 bucket name that you are using as the staging bucket. Additionally, AWS Glue must have access to specific AWS owned S3 buckets for hosting AWS Glue transforms. In this example, the IAM policy uses aws-glue-studio-transforms-510798373988-prod-us-east-1, which is the AWS owned bucket in the us-east-1 Region. Refer to Review IAM permissions needed for ETL jobs for the appropriate bucket name for your Region.

  5. Choose Next.
  6. For Policy name, enter a name (for this post, we use glue-redshift-gsc-policy).
  7. Enter a description, then choose Create policy.
  8. In the navigation pane, choose Roles and Create role.
  9. Choose Custom trust policy and enter the following, then choose Next.
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Effect": "Allow",
                "Principal": {
                    "Service": [
                        "glue.amazonaws.com"
                    ]
                },
                "Action": "sts:AssumeRole"
            }
        ]
    }
    

  10. Search for and select the policy glue-redshift-gsc-policy, then choose Next.
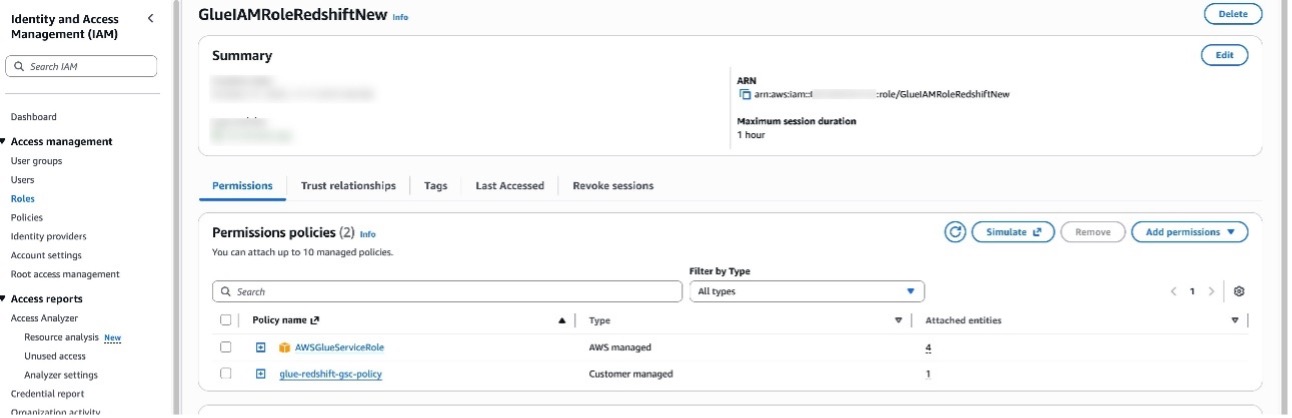
  11. Provide the role name GlueIAMRoleRedshiftNew or another name and relevant Description, then choose Create role.
  12. After the role is created, choose Add permissions and Attach policies.
  13. Search for AWSGlueServiceRole and choose Add Permissions. This policy is typically attached to roles specified when defining crawlers, jobs, and development endpoints.

Screenshot of AWS IAM console showing the policy attachment interface where the AWSGlueServiceRole policy is being added to the GlueIAMRoleRedshiftNew role.

Create secret in Secrets Manager

Complete the following steps to create a Secrets Manager secret:

  1. On the Secrets Manager console, choose Store a new secret.
  2. Select Other type of secret.
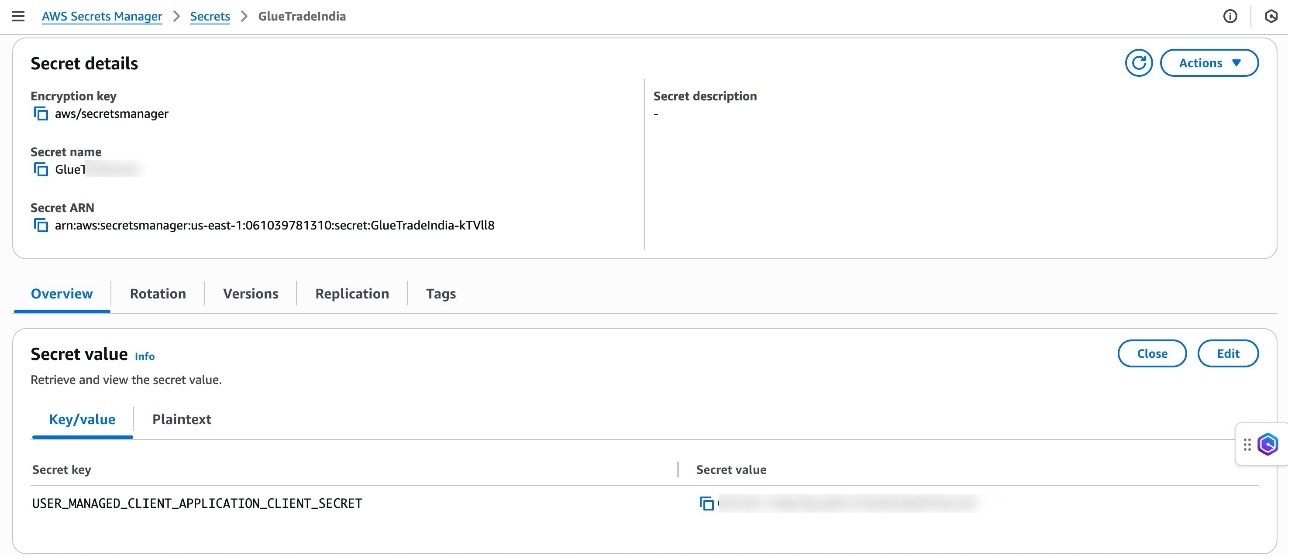
  3. For the customer-managed connected application, the secret should contain the connected application’s consumer secret with USER_MANAGED_CLIENT_APPLICATION_CLIENT_SECRET as the key and the client secret value as created in the previous step.
    Screenshot of AWS Secrets Manager console showing the "Store a new secret" interface with "Other type of secret" selected and a key-value pair entry for USER_MANAGED_CLIENT_APPLICATION_CLIENT_SECRET.
  4. Choose Next.
  5. Enter a secret name and choose Next.
  6. Choose Store.

Create connection to Google Search Console in AWS Glue

To create a connection to Google Search Console in AWS Glue, follow these steps:

  1. Sign in to the AWS Glue console with an authorized email ID with permissions already provided in Google Search Console.
  2. In the navigation pane, choose Data connections.
  3. Under Connections, choose Create connection.
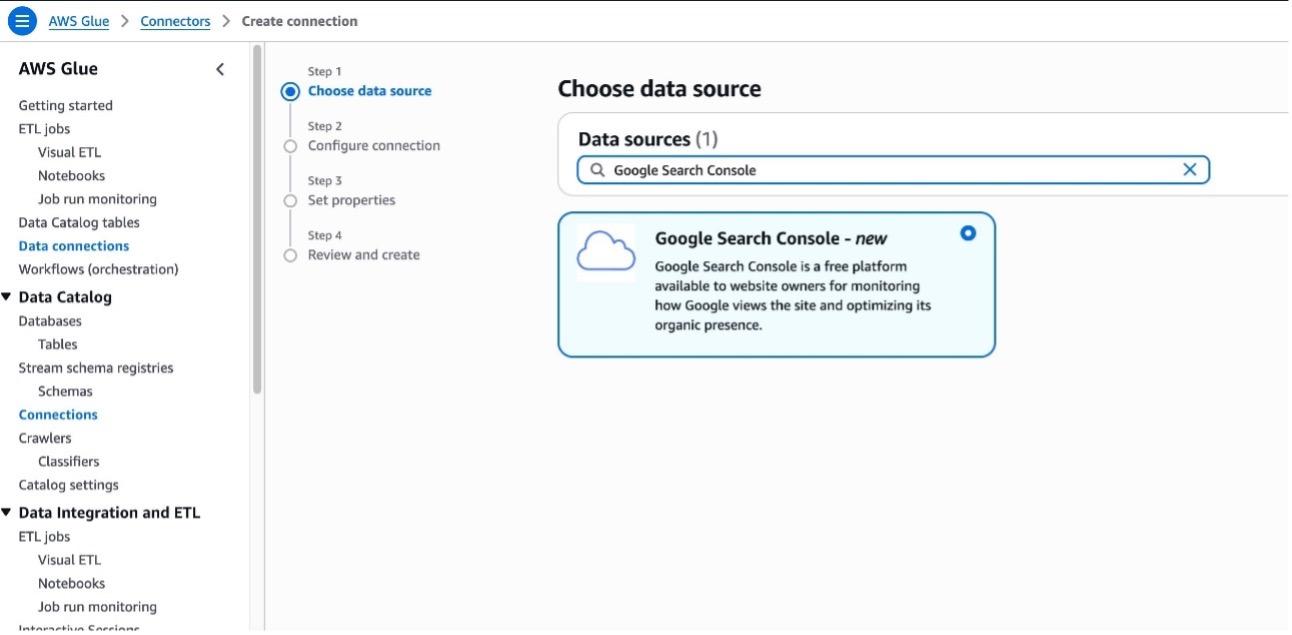
  4. In Data sources, search for Google Search Console and choose Next.
    Screenshot of AWS Glue console showing the Data connections page with Google Search Console selected as a data source in the connection creation wizard.
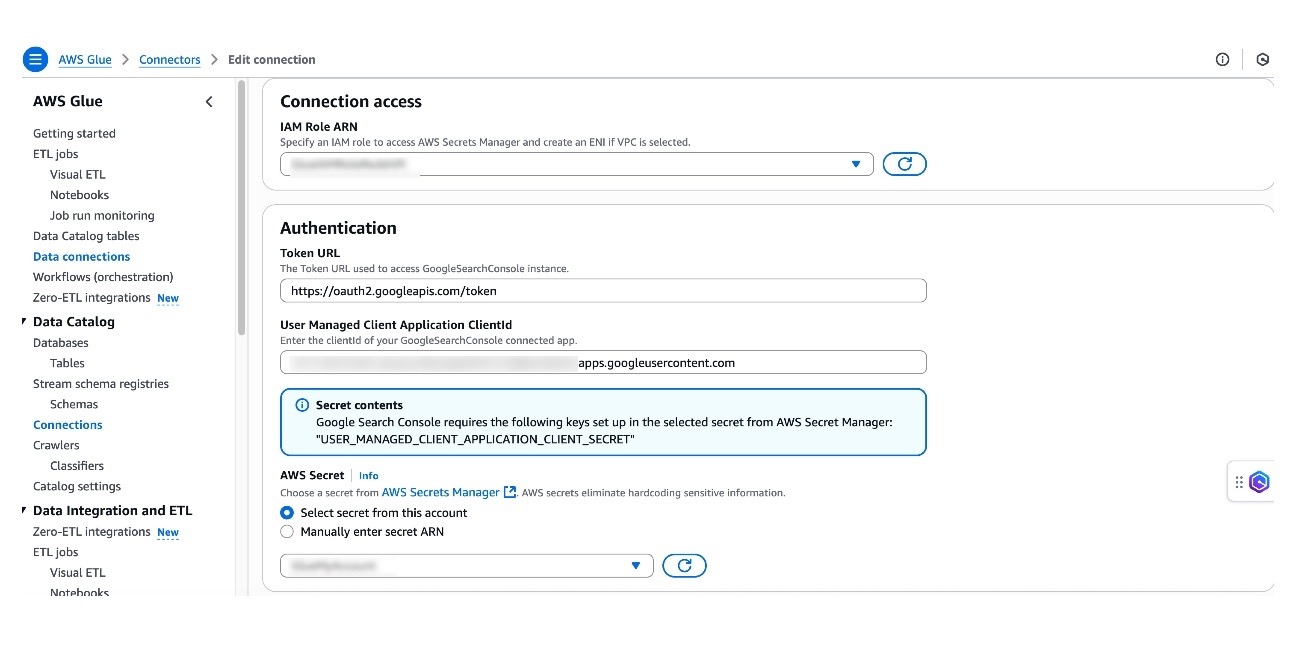
  5. For IAM Role ARN, choose the role created earlier.
  6. For Token URL, use https://oauth2.googleapis.com/token, which is the default value.
  7. For User Managed Client Application ClientId, enter the client ID created earlier while creating the OAuth client.
  8. For AWS Secret, choose the secret created earlier.
  9. If your AWS Glue jobs needs to run in an Amazon virtual private cloud (VPC), provide appropriate details. For more information, refer to Configure a VPC for your ETL job.
    Screenshot of AWS Glue connection configuration form showing fields for IAM Role ARN, Token URL, User Managed Client Application ClientId, AWS Secret selection, and VPC configuration options
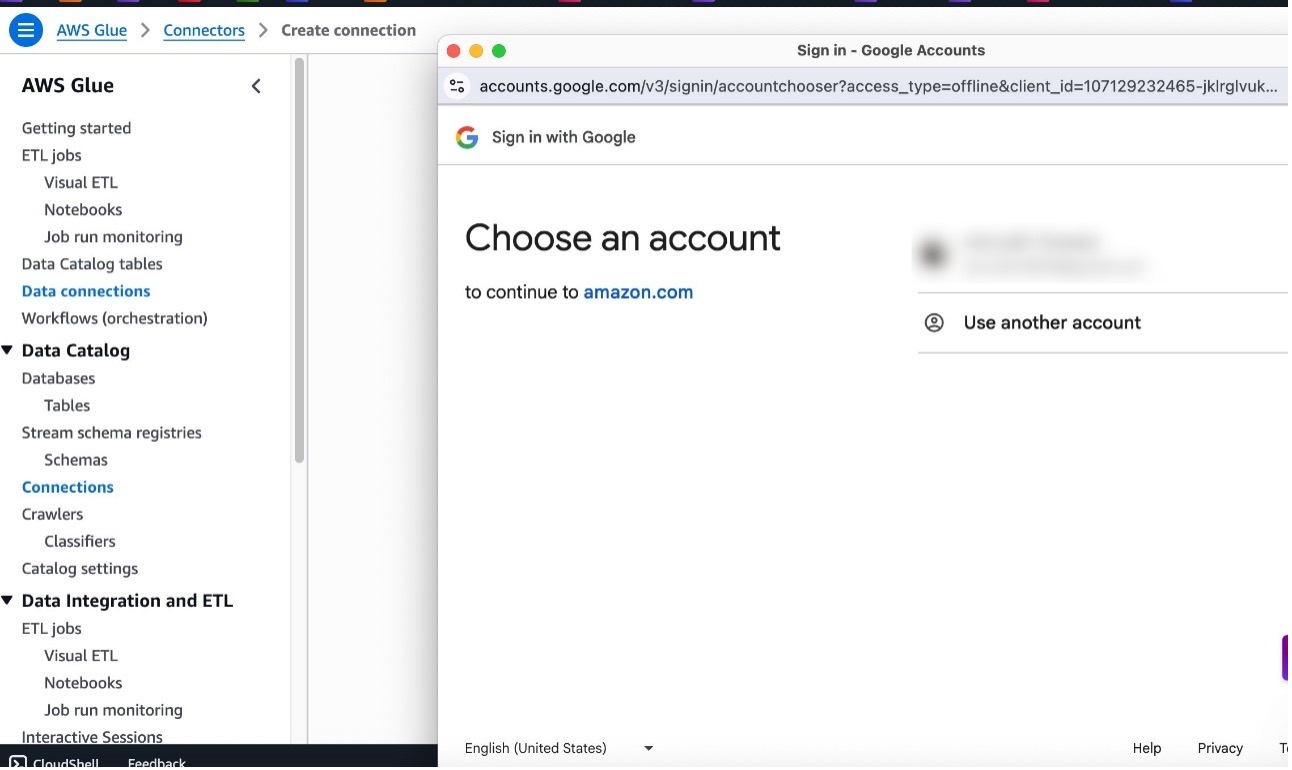
  10. Choose Test connection, choose your Google ID, and choose Continue.
    Google account selection dialog prompting the user to choose which Google account to use for authentication with the AWS Glue connection.
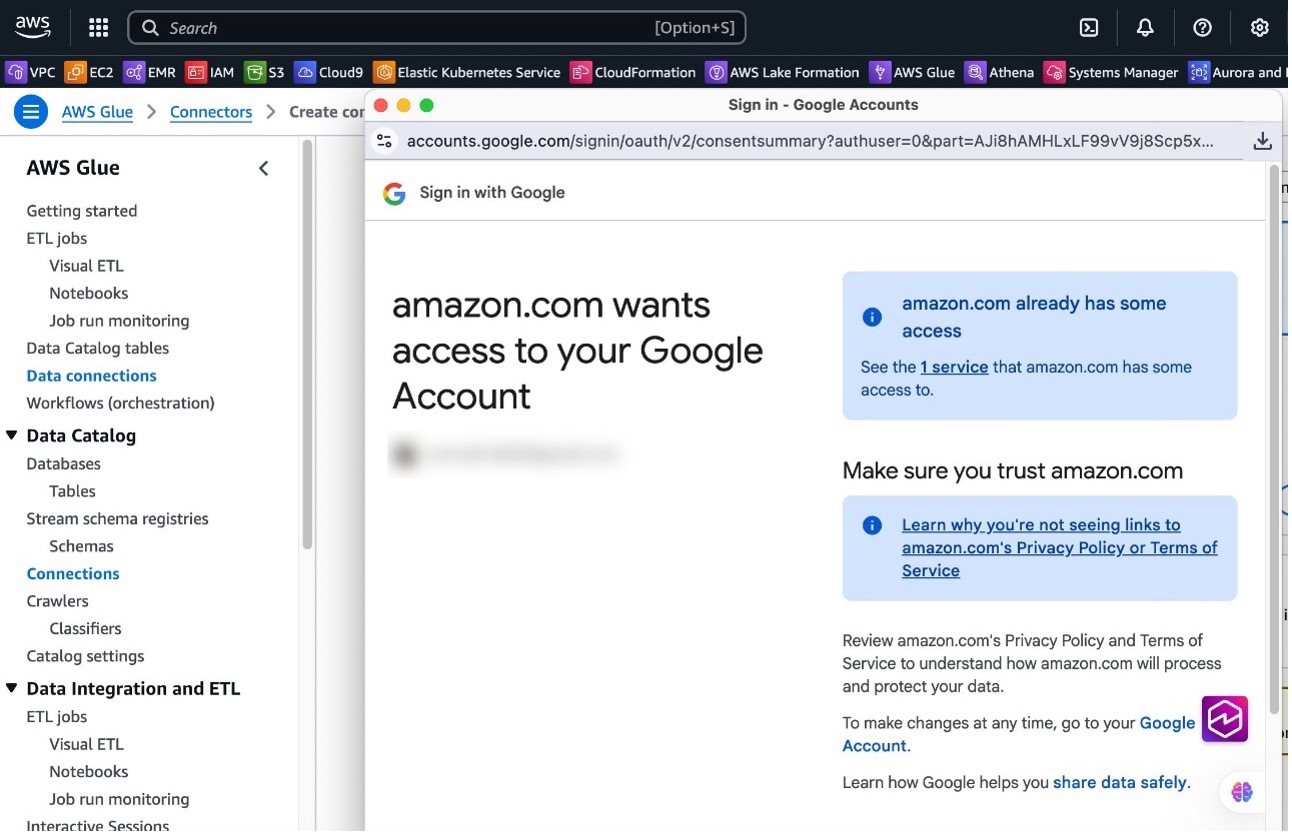
  11. Choose Continue to trust the connection.
    Google OAuth consent screen asking the user to continue and trust the connection between AWS Glue and their Google account.

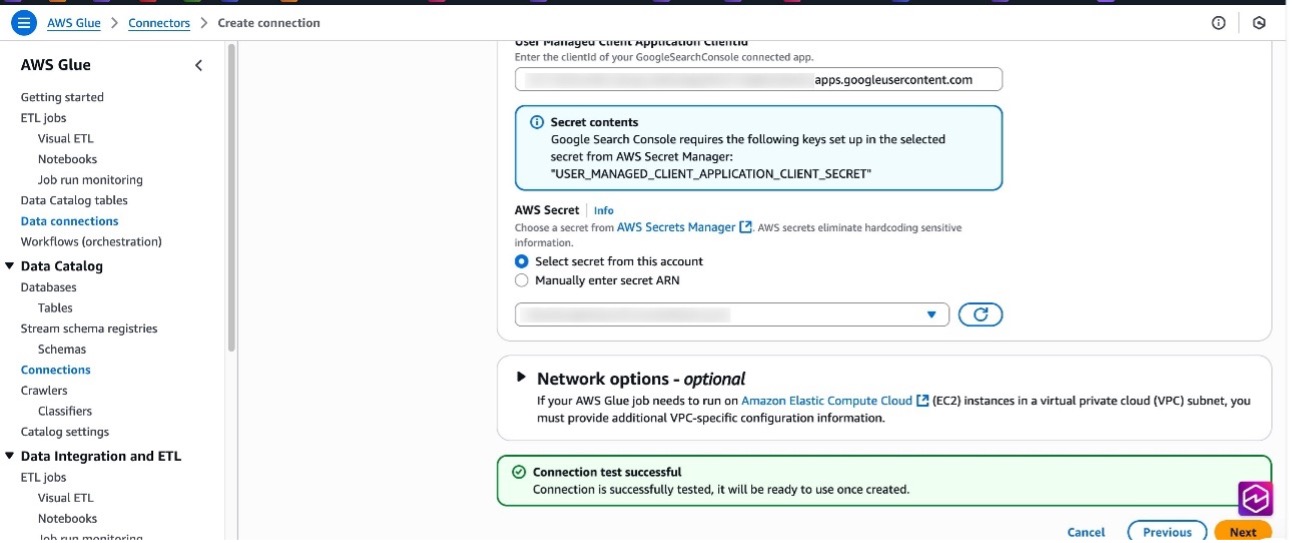
    If the user has authorized access, the connection test will be successful.

    AWS Glue console showing a successful connection test result with a green checkmark indicating the Google Search Console connection was established successfully.

  12. Choose Next.
  13. Provide a connection name and choose Create connection.

Create connection to Amazon Redshift in AWS Glue

Complete the following steps to set up an AWS Glue connection for Amazon Redshift. Refer to Redshift connections for more information.

  1. On the AWS Glue console, in the navigation pane, choose Data connections.
  2. Under Connections, choose Create connection.
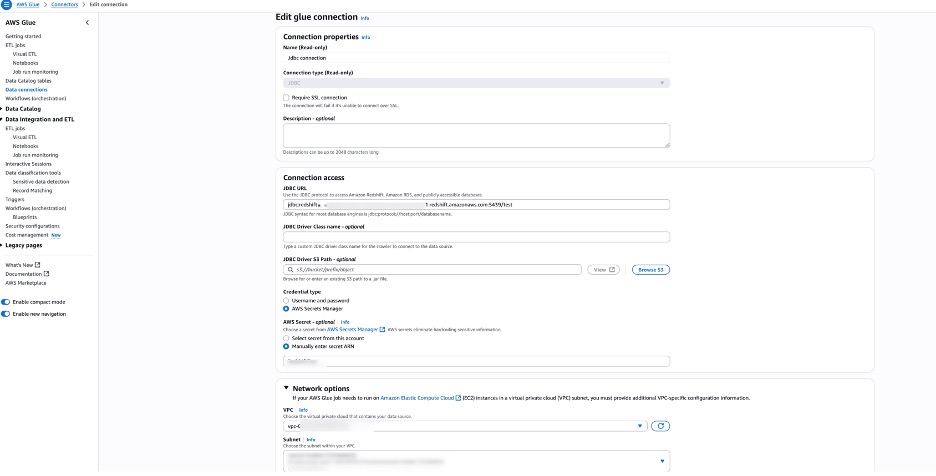
  3. In Data sources, search for JDBC and choose Next. For Amazon Redshift, you can also use Redshift connections. In this post, we use JDBC. In this example, we are using a Redshift provisioned cluster.
  4. Provide the Amazon Redshift JDBC URL and either use a Secrets Manager secret for storing credentials or provide the user name and password directly. As a best practice, it is recommended to use Secrets Manager.
  5. Configure network options with Amazon VPC settings for running the AWS Glue job in a VPC. In this example, we use the same VPC, subnet, and security group where the Redshift cluster is provisioned. All JDBC data stores must be accessible from the VPC subnet. A VPC endpoint is required to access Amazon S3 from within your VPC. If your job needs to access both VPC resources and the public internet, configure a NAT gateway in the VPC.Screenshot of AWS Glue connection configuration for Amazon Redshift showing JDBC URL entry, credentials configuration options (Secrets Manager or direct username/password), and VPC network settings including VPC, subnet, and security group selections.

Set up table and permissions in Amazon Redshift

To set up table and permissions in Amazon Redshift, follow these steps:

  1. On the Amazon Redshift console, choose Query editor v2.
  2. Connect to your existing Redshift cluster.
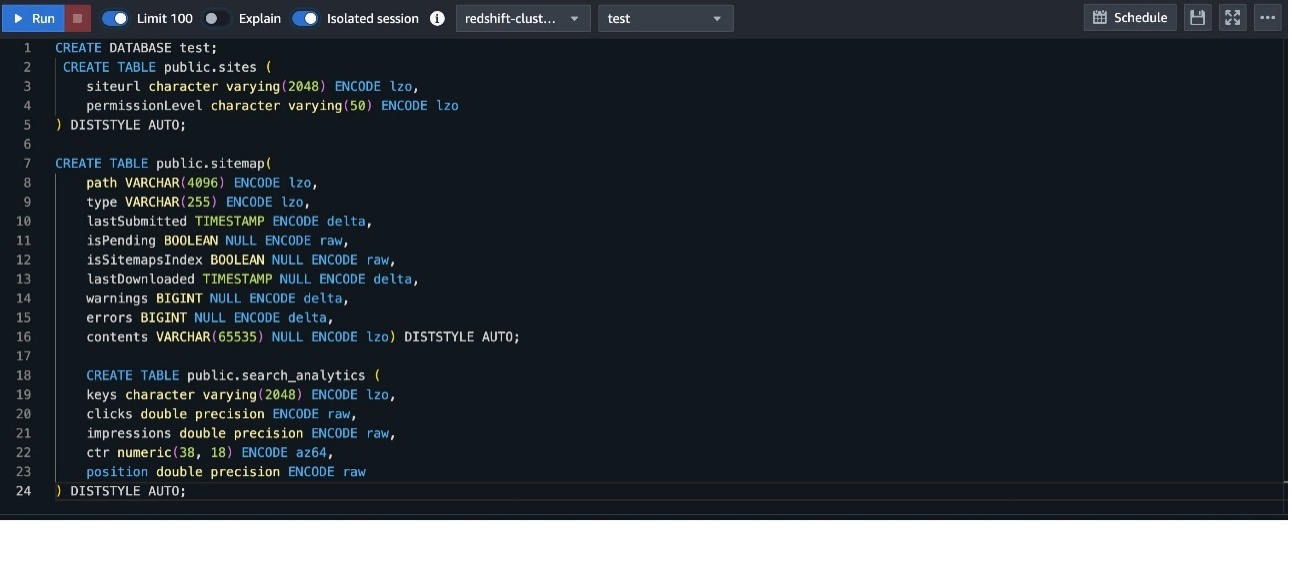
  3. Create a table with the following DDL. For this post, we create a new database named test and create the following tables in the public schema of test database:
    #Create Database command
    CREATE DATABASE test; 
    
    #Sitemap table creation
    CREATE TABLE public.sitemap(
        path VARCHAR(4096) ENCODE lzo,
        type VARCHAR(255) ENCODE lzo,
        lastSubmitted TIMESTAMP ENCODE delta,
        isPending BOOLEAN NULL ENCODE raw,
        isSitemapsIndex BOOLEAN NULL ENCODE raw,
        lastDownloaded TIMESTAMP NULL ENCODE delta,
        warnings BIGINT NULL ENCODE delta,
        errors BIGINT NULL ENCODE delta,
        contents VARCHAR(65535) NULL ENCODE lzo) DISTSTYLE AUTO;
        
    #Search Analytics table creation
    CREATE TABLE public.search_analytics (
        keys character varying(2048) ENCODE lzo,
        clicks double precision ENCODE raw,
        impressions double precision ENCODE raw,
        ctr numeric(38, 18) ENCODE az64,
        position double precision ENCODE raw
    ) DISTSTYLE AUTO;
    
    #Sites table creation
     CREATE TABLE public.sites (
        siteurl character varying(2048) ENCODE lzo,
        permissionLevel character varying(50) ENCODE lzo
    ) DISTSTYLE AUTO;

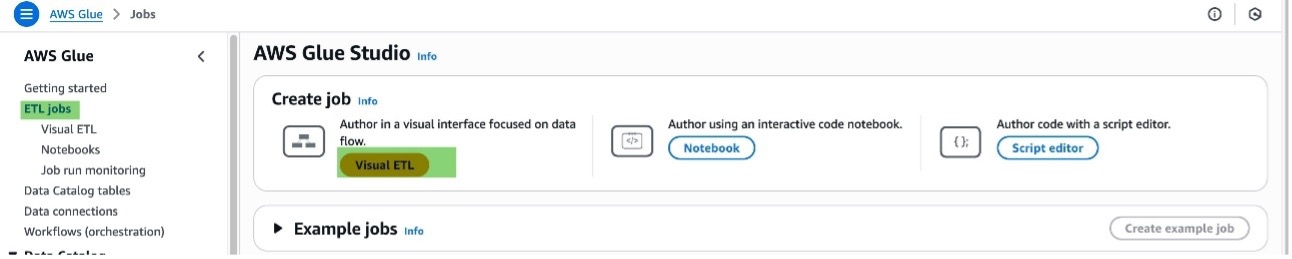
    Screenshot of AWS Glue ETL job visual editor showing the job creation interface with source and target selection options, displaying Google Search Console as source and Amazon Redshift as target.

Create ETL job in AWS Glue

To create a data flow in AWS Glue, follow these steps:

  1. On the AWS Glue console, choose ETL jobs in the navigation pane.
  2. Choose Visual ETL under Create job.
    Each ETL job in AWS Glue is priced based on its duration.

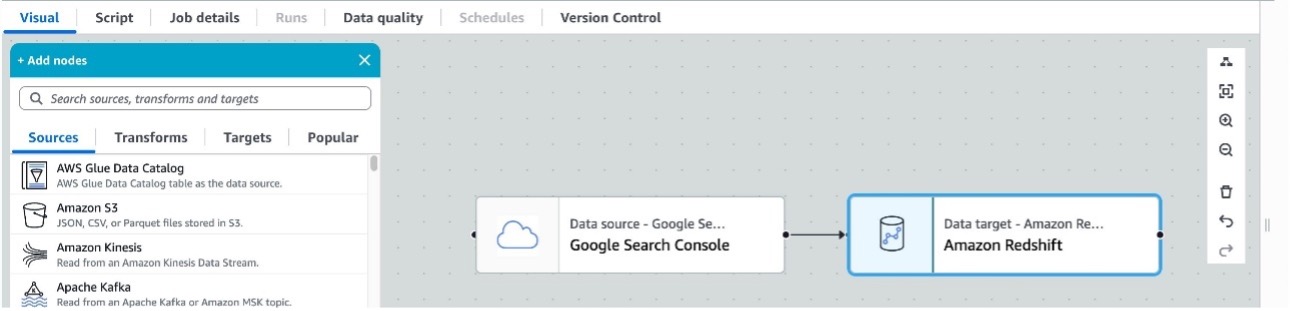
    Screenshot of AWS Glue visual ETL canvas showing a data flow diagram with Google Search Console source node connected to Amazon Redshift target node.

  3. For the source, choose Google Search Console, and for the target, choose Amazon Redshift.
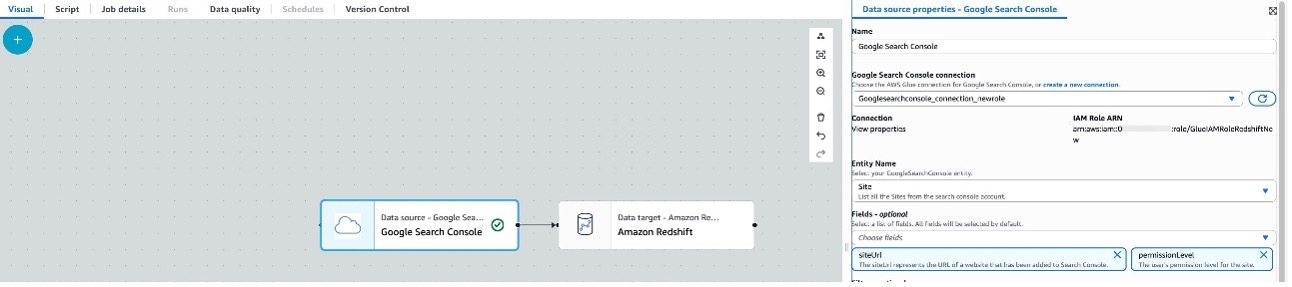
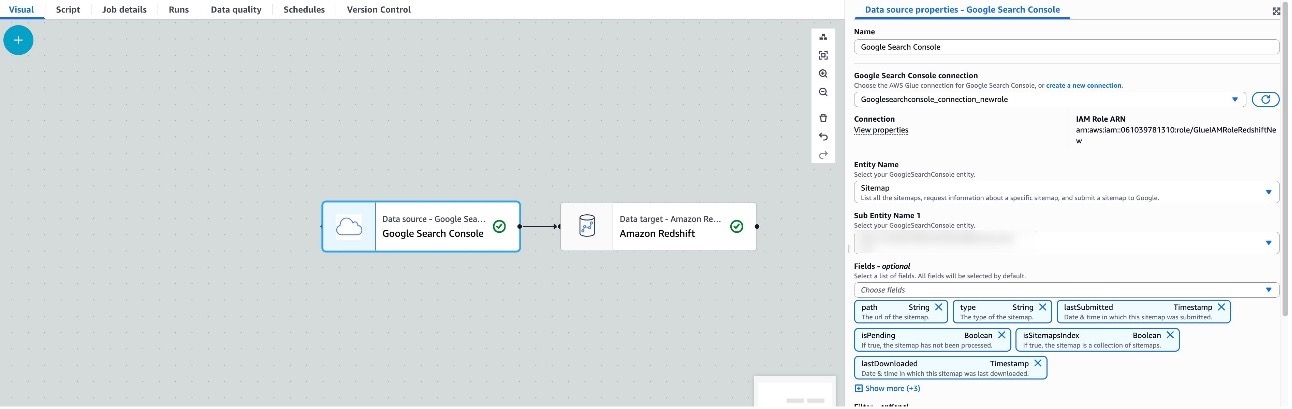
    Screenshot of AWS Glue source node configuration panel showing Google Search Console connection settings with entity selection (Sites) and field selection options (siteUrl and permissionLevel).
  4. Choose Source (Google Search Console) to configure the properties, which opens in the right window pane.
  5. Choose the Google Search Console connection created in the previous sections, and provide the entity name. At the time of writing, there are three supported entities: Search Analytics, Sites, and Sitemaps, with multiple supported fields and operators for each entity. Choose the entity name and the corresponding fields; by default, the connector selects all fields. The example shows selecting the entity Site and corresponding fields siteUrl and permissionLevel.
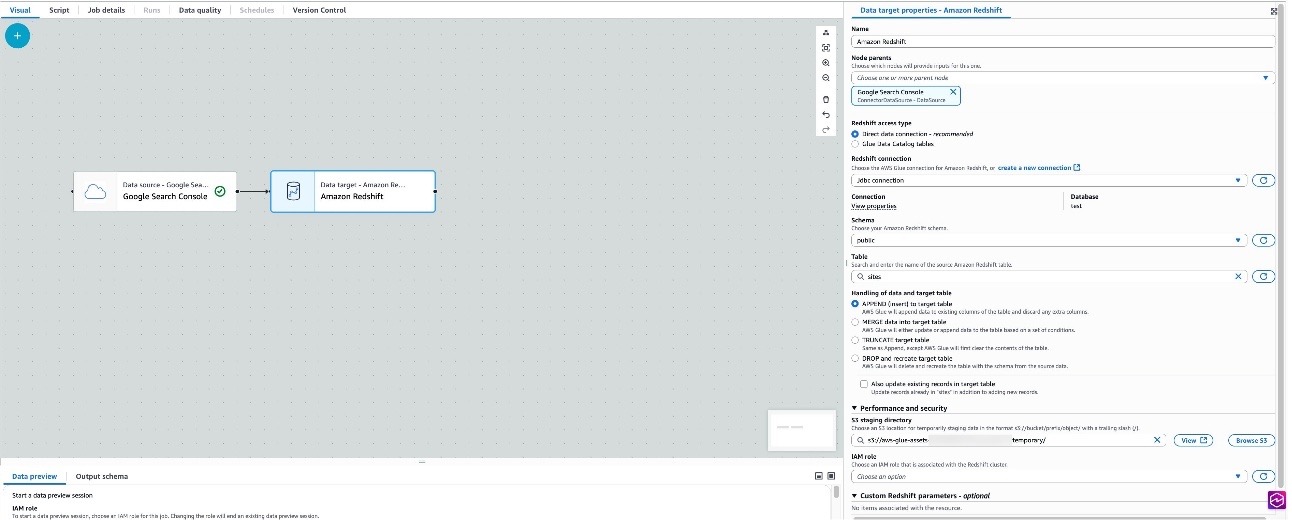
    Screenshot of AWS Glue target node configuration panel showing Amazon Redshift connection settings including schema selection, table name, data handling method (Append to target table), and S3 staging directory configuration.
  6. Choose Target (Amazon Redshift) to configure the properties, which opens in the right pane.
  7. Choose the Amazon Redshift connection, schema, and table name that were created in the previous steps. In this example, we use Append to target table as the method for handling the data. An S3 directory is provided for staging temporary data.
    Screenshot of AWS Glue target node configuration panel showing Amazon Redshift connection settings including schema selection, table name, data handling method (Append to target table), and S3 staging directory configuration.
  8. Navigate to Job details and provide a job name and IAM role (which the job will assume while running). This is the same role created earlier.
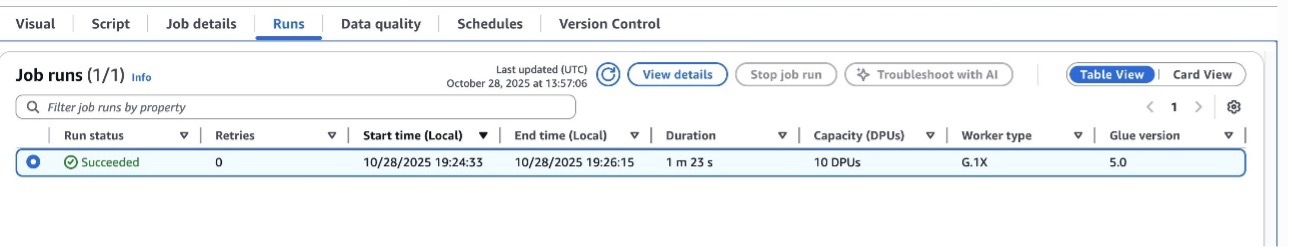
  9. Choose Save and Run. For this example, we use AWS Glue version 5.0, keeping all other configuration values under Job details at their defaults. For this example, we have not implemented any schema mapping, so the columns in Amazon Redshift were created to match the output response for the Search entity.
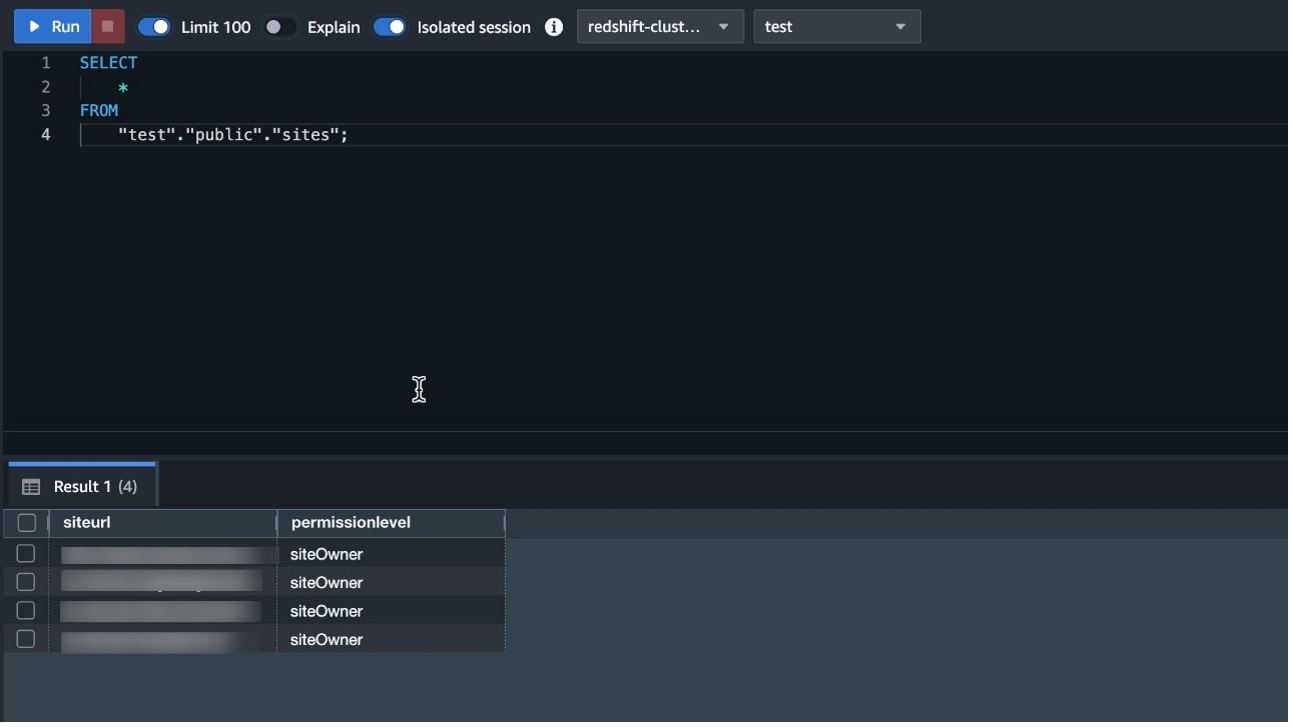
  10. After the job has completed successfully, navigate to Query Editor v2 in Amazon Redshift and query the Sites table to preview the data.
    Screenshot of Amazon Redshift Query Editor v2 showing query results from the Sites table with columns for siteurl and permissionlevel, displaying sample data rows.Screenshot of Amazon Redshift Query Editor v2 showing query results from the Sites table with columns for siteurl and permissionlevel, displaying sample data rows.
  11. In the case of job failures, validate the connections by doing a data preview, and refer to Troubleshooting AWS Glue.
  12. Similar to the Site entity, you can load Sitemap entity data by changing the source properties and destination table in the target Redshift cluster, then choosing Run.
    Screenshot of AWS Glue source node configuration showing Google Search Console entity selection changed to Sitemaps with corresponding fields selected.
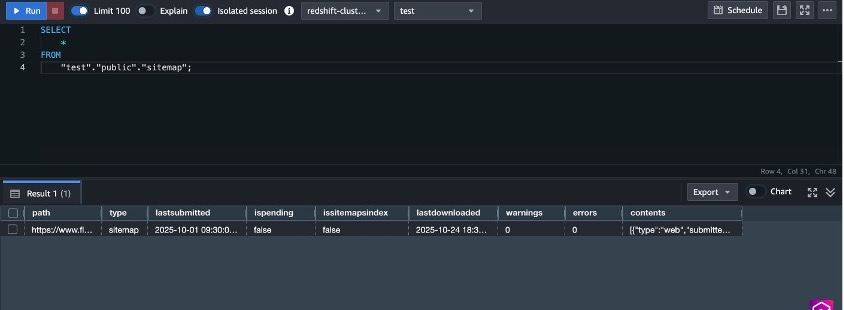
  13. Navigate to Query Editor v2 in Amazon Redshift and query the sitemap table to preview the data.
    Screenshot of Amazon Redshift Query Editor v2 showing query results from the sitemap table with columns including path, type, lastsubmitted, ispending, issitemapsindex, lastdownloaded, warnings, errors, and contents.
  14. Similar to Sitemap, you can load Search Analytics entity data by changing the source properties and destination table in the target Redshift cluster, then choosing Run.
    Screenshot of AWS Glue source node configuration showing Google Search Console entity selection changed to Search Analytics with corresponding fields selected.
  15. Navigate to Query Editor v2 in Amazon Redshift and query the search_analytics table and preview the data.
    Screenshot of Amazon Redshift Query Editor v2 showing query results from the search_analytics table with columns for keys, clicks, impressions, ctr, and position.

Filter predicates with Search Analytics

The Search Analytics entity provides support for multiple filters that can be used to view the traffic data for the sites. The following examples show use of some filter predicates you can use that Google Search Console connections support.

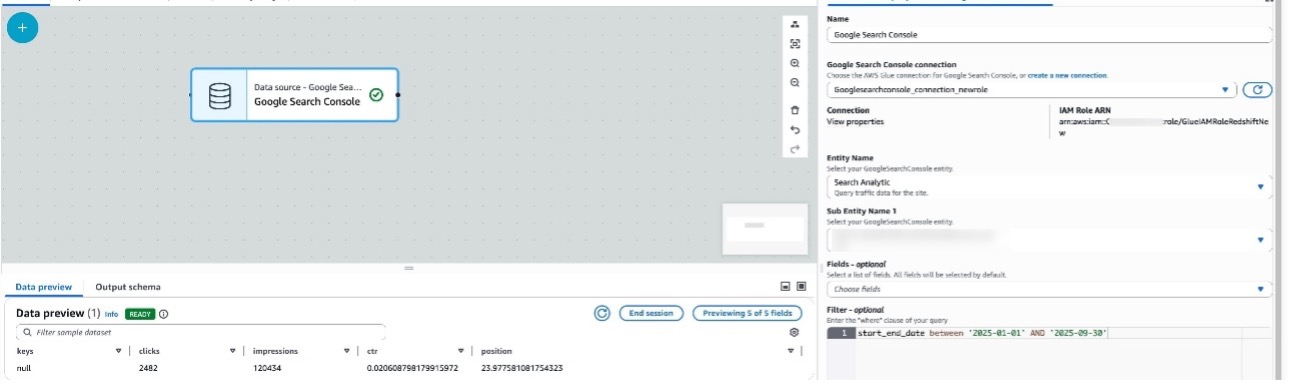
  • start_end_date – The default value for start_end_date is between <30 days ago from the current date> AND <yesterday>. To use a different date range, use the between The following example displays search data from January through September 2025:
    start_end_date between '2025-01-01' AND '2025-09-30'

    Screenshot of AWS Glue source node configuration showing Search Analytics entity with a filter predicate for start_end_date between '2025-01-01' AND '2025-09-30'.

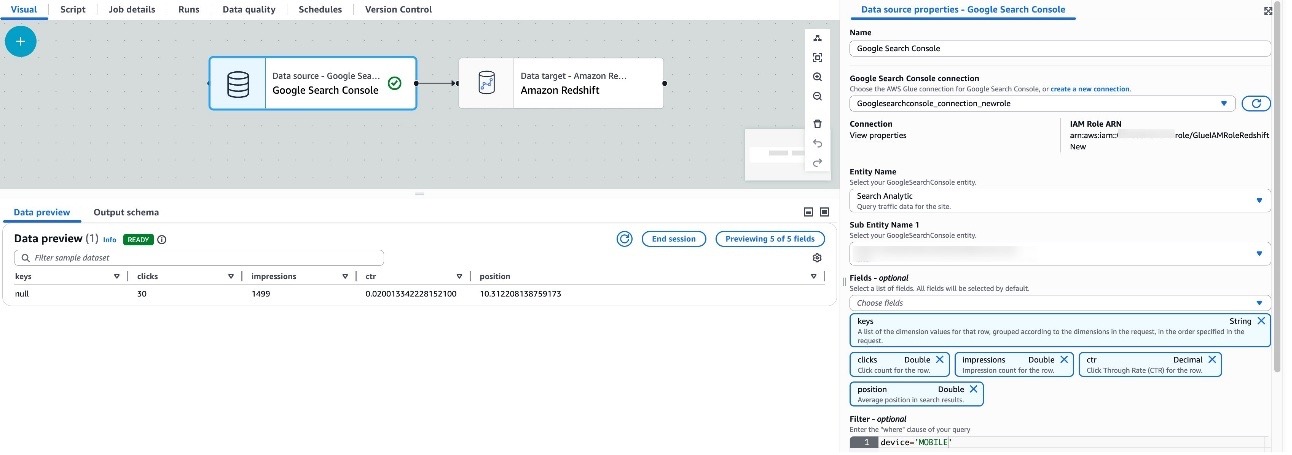
  • device – The device filters result against specified device type like DESKOP, MOBILE, and TABLET:
    device = 'MOBILE'

    Screenshot of AWS Glue source node configuration showing Search Analytics entity with a filter predicate for device = 'MOBILE'.

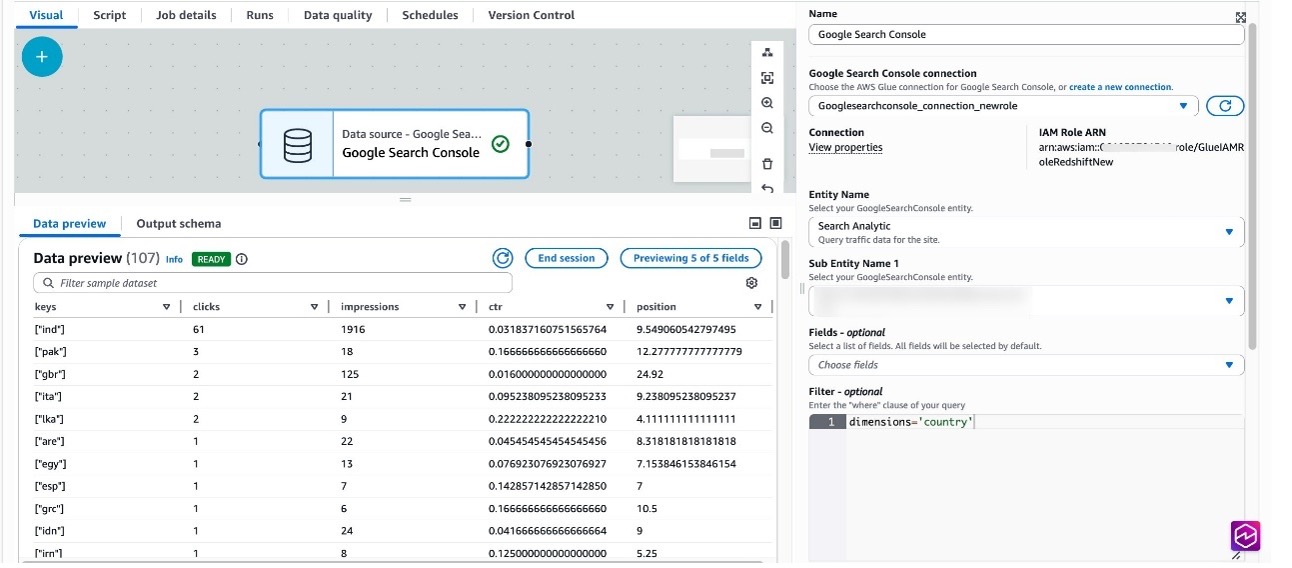
  • country – You can filter against the specified country, as specified by three-letter country code (ISO 3166-1 alpha-3):
    dimensions='country'

    Screenshot of AWS Glue source node configuration showing Search Analytics entity with dimensions set to 'country'.

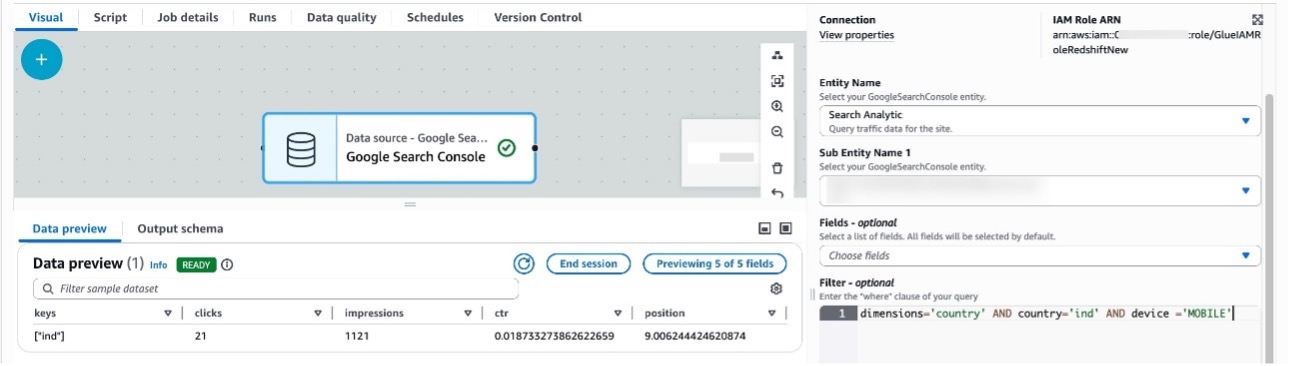
  • dimensions: Dimensions help group zero or more results for filtering search data by country or device. The following example displays search data grouped by country, and also grouping by country and filtering for mobile devices:
    dimensions='country' AND country='ind' AND device ='MOBILE'

    Screenshot of AWS Glue source node configuration showing Search Analytics entity with multiple filter predicates including dimensions='country', country='ind', and device='MOBILE'.

Run analytical queries on Amazon Redshift

In this section, we run analytical queries using aggregated data across different search entities.

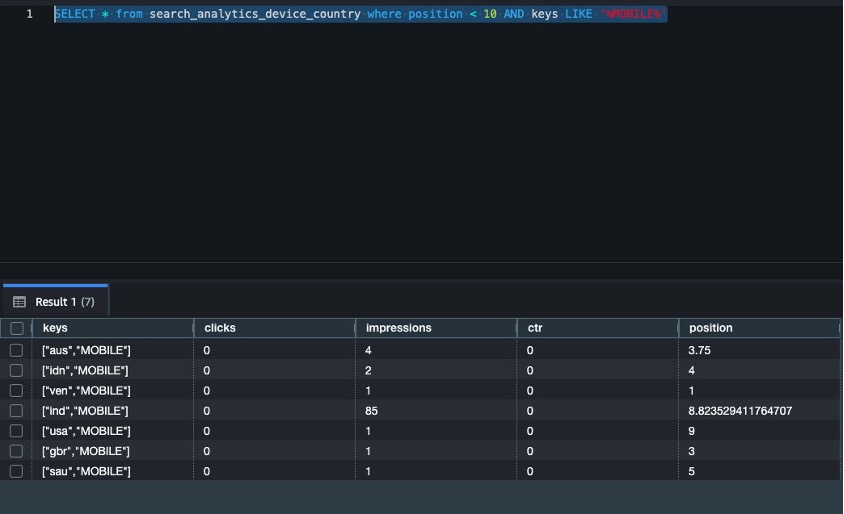
List all countries where site position is less than 10 and device type is MOBILE:

SELECT * from search_analytics_device_country where position < 10 AND keys LIKE '%MOBILE%'

Screenshot of Amazon Redshift Query Editor v2 showing query results for countries where site position is less than 10 and device type is MOBILE, displaying data from the search_analytics_device_country table.

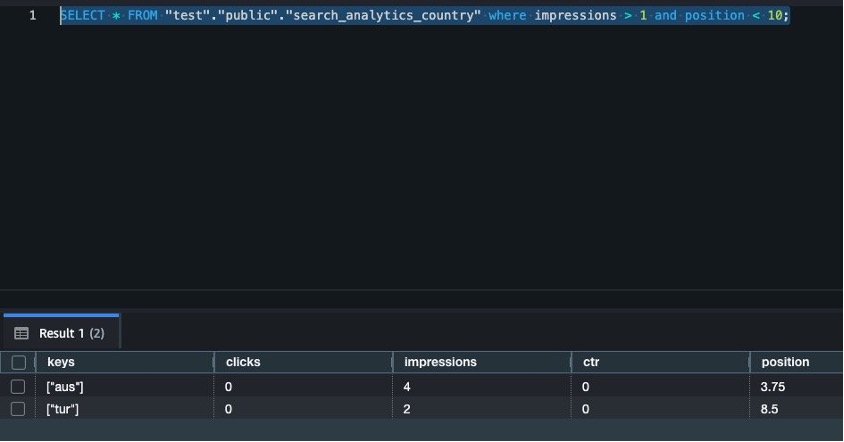
List all countries where impressions are greater than 1 and position is less than 10:

SELECT * FROM "test"."public"."search_analytics_country" where impressions > 1 and position < 10;

Screenshot of Amazon Redshift Query Editor v2 showing query results for countries where impressions are greater than 1 and position is less than 10, displaying data from the search_analytics_country table.

Clean up

To avoid incurring charges, clean up the resources in your AWS account by completing the following steps:

  1. On the AWS Glue console, in the navigation pane, choose Job monitoring.
  2. Stop any running jobs created for Google Search Console connections.
  3. From the list of connections, select the connection name created and delete it.
  4. Delete the Redshift provisioned cluster or the Redshift Serverless workspace and namespace. Amazon Redshift pricing is applied during the cluster’s runtime based on cluster configuration.
  5. Clean up resources in your Google account by deleting the project that contains the Google Project resources. For instructions, refer to Delete your project.

Conclusion

In this post, we walked you through the process of using AWS Glue to integrate data from Google Search Console and write it to Amazon Redshift, a petabyte-scale data warehouse. Whether you’re archiving historical data, performing complex analytics, or preparing data for machine learning, this connector streamlines the process and helps create an integrated data pipeline.

For more information, refer to AWS Glue support for Google Search Console.


About the authors

Anirudh Chawla

Anirudh Chawla

Anirudh is an AWS Analytics Specialist Solutions Architect. He likes to read books, take long walks in nature, and participate in community programs.

Shubham Purwar

Shubham Purwar

Shubham is an AWS Analytics Specialist Solution Architect. In his free time, Shubham loves to spend time with his family and travel around the world.

Shaswat Mandhanya

Shaswat Mandhanya

Shaswat is an AWS Analytics Specialist BD. In his free time, he likes to watch Formula 1 races and travel across the country.

Prabhu G

Prabhu G

Prabhu is a Solutions Architect at AWS. He is an avid supporter of Chennai Super Kings and a big-time fan of MS Dhoni.

Building an AI-powered defense-in-depth security architecture for serverless microservices

Post Syndicated from Roger Nem original https://aws.amazon.com/blogs/security/building-an-ai-powered-defense-in-depth-security-architecture-for-serverless-microservices/

Enterprise customers face an unprecedented security landscape where sophisticated cyber threats use artificial intelligence to identify vulnerabilities, automate attacks, and evade detection at machine speed. Traditional perimeter-based security models are insufficient when adversaries can analyze millions of attack vectors in seconds and exploit zero-day vulnerabilities before patches are available.

The distributed nature of serverless architectures compounds this challenge—while microservices offer agility and scalability, they significantly expand the attack surface where each API endpoint, function invocation, and data store becomes a potential entry point, and a single misconfigured component can provide attackers the foothold needed for lateral movement. Organizations must simultaneously navigate complex regulatory environments where compliance frameworks like GDPR, HIPAA, PCI-DSS, and SOC 2 demand robust security controls and comprehensive audit trails, while the velocity of software development creates tension between security and innovation, requiring architectures that are both comprehensive and automated to enable secure deployment without sacrificing speed.

The challenge is multifaceted:

  • Expanded attack surface: Multiple entry points across distributed services requiring protection against distributed denial of service (DDoS) attacks, injection vulnerabilities, and unauthorized access
  • Identity and access complexity: Managing authentication and authorization across numerous microservices and service-to-service communications
  • Data protection requirements: Encrypting sensitive data in transit and at rest while securely storing and rotating credentials without compromising performance
  • Compliance and data protection: Meeting regulatory requirements through comprehensive audit trails and continuous monitoring in distributed environments
  • Network isolation challenges: Implementing controlled communication paths without exposing resources to the public internet
  • AI-powered threats: Defending against attackers who use AI to automate reconnaissance, adapt attacks in real-time, and identify vulnerabilities at machine speed

The solution lies in defense-in-depth—a layered security approach where multiple independent controls work together to protect your application.

This article demonstrates how to implement a comprehensive AI-powered defense-in-depth security architecture for serverless microservices on Amazon Web Services (AWS). By layering security controls at each tier of your application, this architecture creates a resilient system where no single point of failure compromises your entire infrastructure, designed so that if one layer is compromised, additional controls help limit the impact and contain the incident while incorporating AI and machine learning services throughout to help organizations address and respond to AI-powered threats with AI-powered defenses.

Architecture overview: A journey through security layers

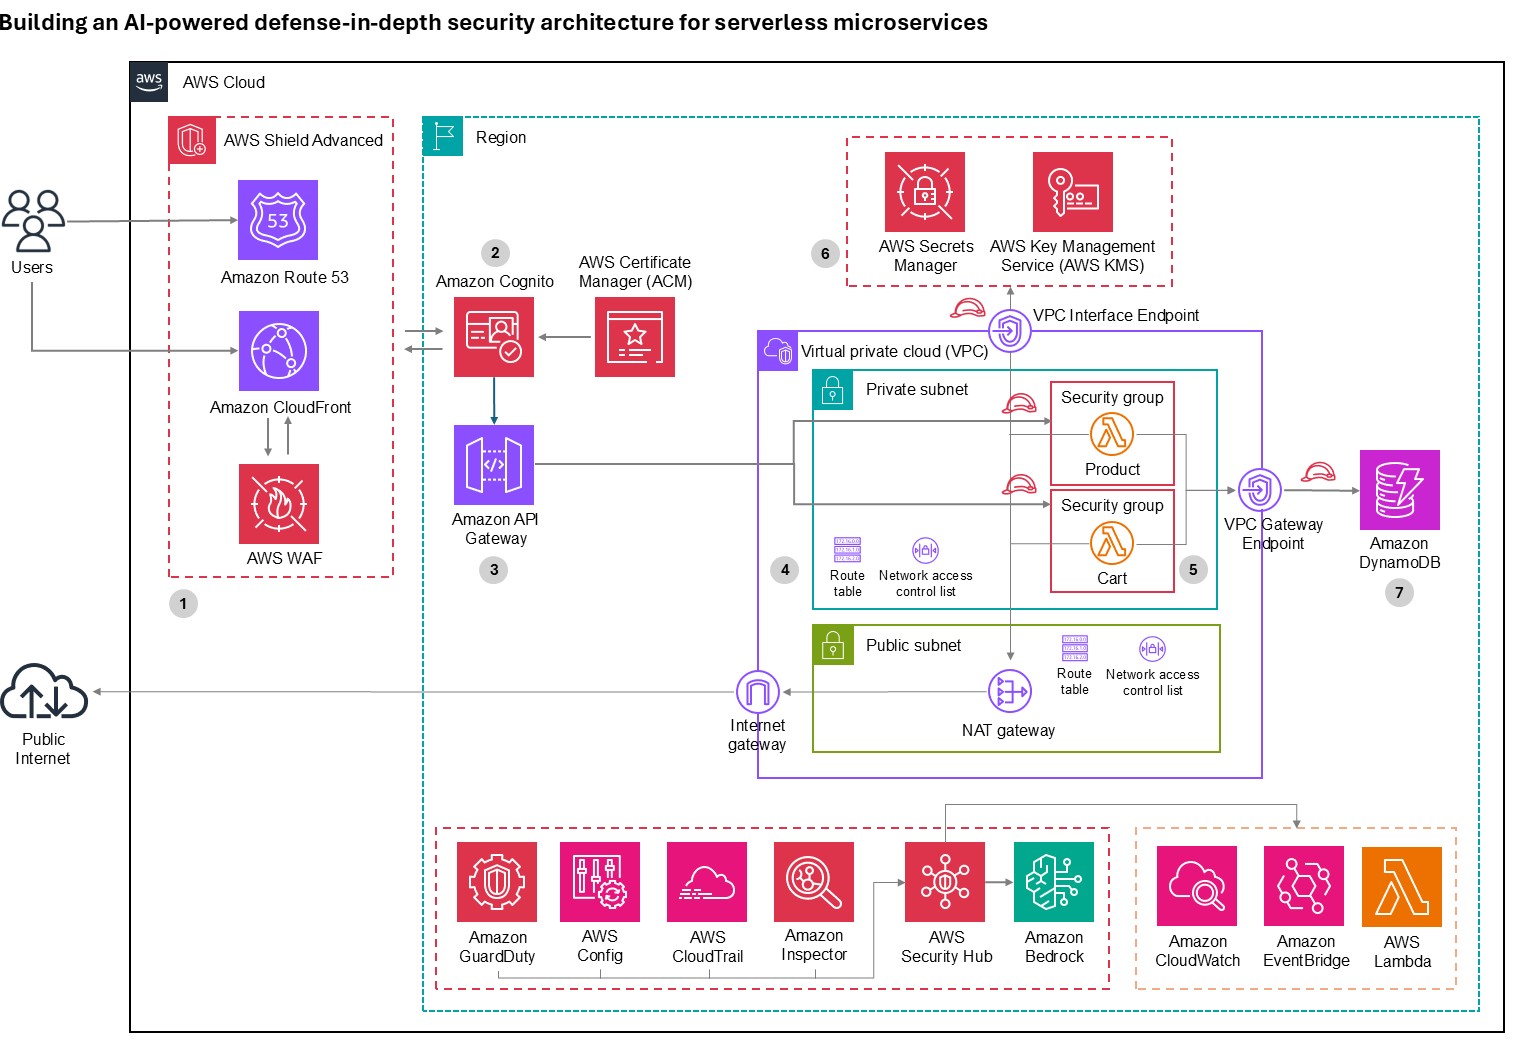
Let’s trace a user request from the public internet through our secured serverless architecture, examining each security layer and the AWS services that protect it. This implementation deploys security controls at seven distinct layers with continuous monitoring and AI-powered threat detection throughout, where each layer provides specific capabilities that work together to create a comprehensive defense-in-depth strategy:

  • Layer 1 blocks malicious traffic before it reaches your application
  • Layer 2 verifies user identity and enforces access policies
  • Layer 3 encrypts communications and manages API access
  • Layer 4 isolates resources in private networks
  • Layer 5 secures compute execution environments
  • Layer 6 protects credentials and sensitive configuration
  • Layer 7 encrypts data at rest and controls data access
  • Continuous monitoring detects threats across layers using AI-powered analysis

Figure 1: Architecture diagram

Figure 1: Architecture diagram

Layer 1: Edge protection

Before requests reach your application, they traverse the public internet where attackers launch volumetric DDoS attacks, SQL injection, cross-site scripting (XSS), and other web exploits. AWS observed and mitigated thousands of distributed denial of service (DDoS) attacks in 2024, with one exceeding 2.3 terabits per second.

  • DDos protection: AWS Shield provides managed DDoS protection for applications running on AWS and is enabled for customers at no cost. AWS Shield Advanced offers enhanced detection, continuous access to the AWS DDoS Response Team (DRT), cost protection during attacks, and advanced diagnostics for enterprise applications.
  • Layer 7 protection: AWS WAF protects against Layer 7 attacks through managed rule groups from AWS and AWS Marketplace sellers that cover OWASP Top 10 vulnerabilities including SQL injection, XSS, and remote file inclusion. Rate-based rules automatically block IPs that exceed request thresholds, protecting against application-layer DDoS and brute force attacks. Geo-blocking capabilities restrict access based on geographic location, while Bot Control uses machine learning to identify and block malicious bots while allowing legitimate traffic.
  • AI for security: Amazon GuardDuty uses generative AI to enhance native security services, implementing AI capabilities to improve threat detection, investigation, and response through automated analysis.
  • AI-powered enhancement: Organizations can build autonomous AI security agents using Amazon Bedrock to analyze AWS WAF logs, reason through attack data, and automate incident response. These agents detect novel attack patterns that signature-based systems miss, generate natural language summaries of security incidents, automatically recommend AWS WAF rule updates based on emerging threats, correlate attack indicators across distributed services to identify coordinated campaigns, and trigger appropriate remediation actions based on threat context. This helps enable more proactive threat detection and response capabilities, reducing mean time to detection and response.

Layer 2: Verifying identity

After requests pass edge protection, you must verify user identity and determine resource access. Traditional username/password authentication is vulnerable to credential stuffing, phishing, and brute force attacks, requiring robust identity management that supports multiple authentication methods and adaptive security responding to risk signals in real time.

Amazon Cognito provides comprehensive identity and access management for web and mobile applications through two components:

  • User pools offer a fully managed user directory handling registration, sign-in, multi-factor authentication (MFA), password policies, social identity provider integration, SAML and OpenID Connect federation for enterprise identity providers, and advanced security features including adaptive authentication and compromised credential detection.
  • Identity pools grant temporary, limited-privilege AWS credentials to users for secure direct access to AWS services without exposing long-term credentials.

Amazon Cognito adaptive authentication uses machine learning to detect suspicious sign-in attempts by analyzing device fingerprinting, IP address reputation, geographic location anomalies, and sign-in velocity patterns, then allows sign-in, requires additional MFA verification, or blocks attempts based on risk assessment. Compromised credential detection automatically checks credentials against databases of compromised passwords and blocks sign-ins using known compromised credentials. MFA supports both SMS-based and time-based one-time password (TOTP) methods, significantly reducing account takeover risk.

For advanced behavioral analysis, organizations can use Amazon Bedrock to analyze patterns across extended timeframes, detecting account takeover attempts through geographic anomalies, device fingerprint changes, access pattern deviations, and time-of-day anomalies.

Layer 3: The application front door

An API gateway serves as your application’s entry point. It must handle request routing, throttling, API key management, encryption and it needs to integrate seamlessly with your authentication layer and provide detailed logging for security auditing while maintaining high performance and low latency.

  • Amazon API Gateway is a fully managed service for creating, publishing, and securing APIs at scale, providing critical security capabilities including SSL/TLS encryption with AWS Certificate Manager (ACM) to automatically handle certificate provisioning, renewal, and deployment. Request throttling and quota management protects backend services through configurable burst and rate limits with usage quotas per API key or client to prevent abuse, while API key management controls access from partner systems and third-party integrations. Request/response validation uses JSON Schema to validate data before reaching AWS Lambda functions, preventing malformed requests from consuming compute resources while seamless integration with Amazon Cognito validates JSON Web Tokens (JWTs) and enforces authentication requirements before requests reach application logic.
  • GuardDuty provides AI-powered intelligent threat detection by analyzing API invocation patterns and identifying suspicious activity including credential exfiltration using machine learning. For advanced analysis, Amazon Bedrock analyzes API Gateway metrics and Amazon CloudWatch logs to identify unusual HTTP 4XX error spikes (for example, 403 Forbidden) that might indicate scanning or probing attempts, geographic distribution anomalies, endpoint access pattern deviations, time-series anomalies in request volume, or suspicious user agent patterns.

Layer 4: Network isolation

Application logic and data must be isolated from direct internet access. Network segmentation is designed to limit lateral movement if a security incident occurs, helping to prevent compromised components from easily accessing sensitive resources.

  • Amazon Virtual Private Cloud (Amazon VPC) provides isolated network environments implementing a multi-tier architecture with public subnets for NAT gateways and application load balancers with internet gateway routes, private subnets for Lambda functions and application components accessing the internet through NAT Gateways for outbound connections, and data subnets with the most restrictive access controls. Lambda functions run in private subnets to prevent direct internet access, VPC flow logs capture network traffic for security analysis, security groups provide stateful firewalls following least privilege principles, Network ACLs add stateless subnet-level firewalls with explicit deny rules, and VPC endpoints enable private connectivity to Amazon DynamoDB, AWS Secrets Manager, and Amazon S3 without traffic leaving the AWS network.
  • GuardDuty provides AI-powered network threat detection by continuously monitoring VPC Flow Logs, CloudTrail logs, and DNS logs using machine learning to identify unusual network patterns, unauthorized access attempts, compromised instances, and reconnaissance activity, now including generative AI capabilities for automated analysis and natural language security queries.

Layer 5: Compute security

Lambda functions executing your application code and often requiring access to sensitive resources and credentials must be protected against code injection, unauthorized invocations, and privilege escalation. Additionally, functions must be monitored for unusual behavior that might indicate compromise.

Lambda provides built-in security features including:

  • AWS Identity and Access Management (IAM) execution roles that define precise resource and action access following least privilege principles
  • Resource-based policies that control which services and accounts can invoke functions to prevent unauthorized invocations
  • Environment variable encryption using AWS Key Management Services (AWS KMS) for variables at rest while sensitive data should use Secrets Manager function isolation designed so that each execution runs in isolated environments preventing cross-invocation data access
  • VPC integration enabling functions to benefit from network isolation and security group controls
  • Runtime security with automatically patched and updated managed runtimes
  • Code signing with AWS Signer digitally signing deployment packages for code integrity and cryptographic verification against unauthorized modifications

AI-powered code security: Amazon CodeGuru Security combines machine learning and automated reasoning to identify vulnerabilities including OWASP Top 10 and CWE Top 25 issues, log injection, secrets, and insecure AWS API usage. Using deep semantic analysis trained on millions of lines of Amazon code, it employs rule mining and supervised ML models combining logistic regression and neural networks for high true-positive rates.

Vulnerability management: Amazon Inspector provides automated vulnerability management, continuously scanning Lambda functions for software vulnerabilities and network exposure, using machine learning to prioritize findings and provide detailed remediation guidance.

Layer 6: Protecting credentials

Applications require access to sensitive credentials including database passwords, API keys, and encryption keys. Hardcoding secrets in code or storing them in environment variables creates security vulnerabilities, requiring secure storage, regular rotation, authorized-only access, and comprehensive auditing for compliance.

  • Secrets Manager protects access to applications, services, and IT resources without managing hardware security modules (HSMs). It provides centralized secret storage for database credentials, API keys, and OAuth tokens in an encrypted repository using AWS KMS encryption at rest.
  • Automatic secret rotation configures rotation for database credentials, automatically updating both the secret store and target database without application downtime.
  • Fine-grained access control uses IAM policies to control which users and services access specific secrets, implementing least-privilege access.
  • Audit trails log secret access in AWS CloudTrail for compliance and security investigations. VPC endpoint support is designed so that secret retrieval traffic doesn’t leave the AWS network.
  • Lambda integration enables functions to retrieve secrets programmatically at runtime, designed so that secrets aren’t stored in code or configuration files and can be rotated without redeployment.
  • GuardDuty provides AI-powered monitoring, detecting anomalous behavior patterns that could indicate credential compromise or unauthorized access.

Layer 7: Data protection

The data layer stores sensitive business information and customer data requiring protection both at rest and in transit. Data must be encrypted, access tightly controlled, and operations audited, while maintaining resilience against availability attacks and high performance.

Amazon DynamoDB is a fully managed NoSQL database providing built-in security features including:

  • Encryption at rest (using AWS-owned, AWS managed, or customer managed KMS keys)
  • Encryption in transit (TLS 1.2 or higher)
  • Fine-grained access control through IAM policies with item-level and attribute-level permissions
  • VPC endpoints for private connectivity
  • Point-in-Time Recovery for continuous backups
  • Streams for audit trails
  • Backup and disaster recovery capabilities
  • Global Tables for multi-AWS Region, multi-active replication designed to provide high availability and low-latency global access

GuarDuty and Amazon Bedrock provide AI-powered data protection:

  • GuardDuty monitors DynamoDB API activity through CloudTrail logs using machine learning to detect anomalous data access patterns including unusual query volumes, access from unexpected geographic locations, and data exfiltration attempts.
  • Amazon Bedrock analyzes DynamoDB Streams and CloudTrail logs to identify suspicious access patterns, correlate anomalies across multiple tables and time periods, generate natural language summaries of data access incidents for security teams, and recommend access control policy adjustments based on actual usage patterns versus configured permissions. This helps transform data protection from reactive monitoring to proactive threat hunting that can detect compromised credentials and insider threats.

Continuous monitoring

Even with comprehensive security controls at every layer, continuous monitoring is essential to detect threats that bypass defenses. Security requires ongoing real-time visibility, intelligent threat detection, and rapid response capabilities rather than one-time implementation.

  • GuardDuty protects your AWS accounts, workloads, and data with intelligent threat detection.
  • CloudWatch provides comprehensive monitoring and observability, collecting metrics, monitoring log files, setting alarms, and automatically reacting to AWS resource changes.
  • CloudTrail provides governance, compliance, and operational auditing by logging all API calls in your AWS account, creating comprehensive audit trails for security analysis and compliance reporting.
  • AI-powered enhancement with Amazon Bedrock provides automated threat analysis; generating natural language summaries of GuardDuty findings and CloudWatch logs, pattern recognition identifying coordinated attacks across multiple security signals, incident response recommendations based on your architecture and compliance requirements, security posture assessment with improvement recommendations, and automated response through Lambda and Amazon EventBridge that isolates compromised resources, revokes suspicious credentials, or notifies security teams through Amazon SNS when threats are detected.

Conclusion

Securing serverless microservices presents significant challenges, but as demonstrated, using AWS services alongside AI-powered capabilities creates a resilient defense-in-depth architecture that protects against current and emerging threats while proving that security and agility are not mutually exclusive.

Security is an ongoing process—continuously monitor your environment, regularly review security controls, stay informed about emerging threats and best practices, and treat security as a fundamental architectural principle rather than an afterthought.

Further reading

If you have feedback about this blog post, submit them in the Comments section below. If you have questions about using this solution, start a thread in the EventBridge, GuardDuty, or Security Hub forums, or contact AWS Support.

Roger Nem
Roger Nem

Roger is an Enterprise Technical Account Manager (TAM) supporting Healthcare & Life Science customers at Amazon Web Services (AWS). As a Security Technical Field community specialist, he helps enterprise customers design secure cloud architectures aligned with industry best practices. Beyond his professional pursuits, Roger finds joy in quality time with family and friends, nurturing his passion for music, and exploring new destinations through travel.

Matching your Ingestion Strategy with your OpenSearch Query Patterns

Post Syndicated from Rakan Kandah original https://aws.amazon.com/blogs/big-data/matching-your-ingestion-strategy-with-your-opensearch-query-patterns/

Choosing the right indexing strategy for your Amazon OpenSearch Service clusters helps deliver low-latency, accurate results while maintaining efficiency. If your access patterns require complex queries, it’s best to re-evaluate your indexing strategy.

In this post, we demonstrate how you can create a custom index analyzer in OpenSearch to implement autocomplete functionality efficiently by using the Edge n-gram tokenizer to match prefix queries without using wildcards.

What is an index analyzer?

Index analyzers are used to analyze text fields during ingestion of a document. The analyzer outputs the terms you can use to match queries

By default, OpenSearch indexes your data using the standard index analyzer. The standard index analyzer splits tokens on spaces, converts tokens to lowercase, and removes most punctuation. For some use cases (like log analytics), the standard index analyzer might be all you need.

Standard Index Analyzer

Let’s look at what the standard index analyzer does. We’ll use the _analyze API to test how the standard index analyzer tokenizes the sentence “Standard Index Analyzer.”

Note: You can run all the commands in this post using OpenSearch DevTools in the OpenSearch Dashboard.

GET /_analyze
{
  "analyzer": "standard",
  "text": "Standard Index Analyzer."
}
#========
#Results
#========
{
  "tokens": [
    {
      "token": "standard",
      "start_offset": 0,
      "end_offset": 8,
      "type": "<ALPHANUM>",
      "position": 0
    },
    {
      "token": "index",
      "start_offset": 9,
      "end_offset": 14,
      "type": "<ALPHANUM>",
      "position": 1
    },
    {
      "token": "analyzer",
      "start_offset": 15,
      "end_offset": 23,
      "type": "<ALPHANUM>",
      "position": 2
    }
  ]
}

Notice how each word was lowercased and the period (punctuation) was removed.

Creating your own index analyzer

OpenSearch offers a large number of built in analyzers that you can use for different access patterns. It also lets you build your own custom analyzer, configured for your specific search needs. In the following example, we are going to configure a custom analyzer that returns partial word matches for a list of addresses. The analyzer is specifically designed for autocomplete functionality, enabling end users to quickly find addresses without having to type out (or remember) an entire address. Autocomplete allows OpenSearch to effectively complete the search term based off matched prefixes.

First, create an index called standard_index_test:

PUT standard_index_test
{
  "mappings": {
    "properties": {
      "text_entry": {
        "type": "text",
        "analyzer": "standard"
      }
    }
  }
}

Specifying the analyzer as standard is not required because the standard analyzer is the default analyzer.

To test, bulk add some data to our standard_index_test that we created.

POST _bulk
{"index":{"_index":"standard_index_test"}} 
{"text_entry": "123 Amazon Street Seattle, Wa 12345 "} 
{"index":{"_index":"standard_index_test"}}
{"text_entry": "456 OpenSearch Drive Anytown, Ny 78910"}
{"index":{"_index":"standard_index_test"}}
{"text_entry": "789 Palm way Ocean Ave, Ca 33345"}
{"index":{"_index":"standard_index_test"}}
{"text_entry": "987 Openworld Street, Tx 48981"}

Query this data using the text “ope”.

GET standard_index_test/_search
{
  "query": {
    "match": {
      "text_entry": {
        "query": "ope"
      }
    }
  }
}
#========
#Results
#========
{
  "took": 2,
  "timed_out": false,
  "_shards": {
    "total": 5,
    "successful": 5,
    "skipped": 0,
    "failed": 0
  },
  "hits": {
    "total": {
      "value": 0,
      "relation": "eq"
    },
    "max_score": n`ull,
    "hits": [] # No matches 
  }
}

When searching for the term “ope”, we don’t get any matches. To see why, we can dive a little deeper into the standard index analyzer and see how our text is being tokenized. Test the standard index analyzer with the address “456 OpenSearch Drive Anytown, Ny 78910”.

POST standard_index_test/_analyze
{
  "analyzer": "standard",
  "text": "456 OpenSearch Drive Anytown, Ny 78910"
}
#========
#Results
#========
  "tokens":
      "456" 
      "opensearch" 
      "drive" 
      "anytown"
      "ny" 
      "78910"

The standard index analyzer has tokenized the address into individual terms: 456, opensearch, drive and so on. That means, unless you search for an individual token (like 456 or opensearch) o, op, ope , and even open won’t yield any results. One option is to use wildcards while still using the standard index analyzer for indexing:

GET standard_index_test/_search
{
  "query": {
    "wildcard": {
      "text_entry": "ope*"
    }
  }
}

The wildcard query would match “456 OpenSearch Drive Anytown, Ny 78910” but wildcard queries can be resource intensive and slow. Querying for ope* in OpenSearch results in iterating over each term in the index, bypassing optimizations of inverted index lookups. This results in higher memory usage and slower performance. To improve the performance of our query execution and search experience, we can use an index analyzer that better suits our access patterns.

Edge n-gram

The Edge n-gram tokenizer helps you find partial matches and avoids the use of wildcards by tokenizing prefixes of a single word. For example, the input word coffee is expanded into all its prefixes, c, co , cof, and so on. It can limit the prefixes to those between a minimum (min_gram) and maximum (max_gram) length. So with min_gram=3 and max_gram=5, it will expand “coffee” to cof, coff, and coffe.

Create a new index called custom_index with our own custom index analyzer that uses Edge n-grams. Set the minimum token length (min_gram) to 3 characters, and the maximum token length (max_gram) to 20 characters. The min_gram and max_gram sets the minimum and maximum returned token length respectively. You should select the min_gram and max_gram based off your access patterns. In this example, we’re searching for the term “ope” so we don’t need to set the minimum length to anything less than 3 since we’re not searching for terms like o or op. Setting the min_gram too low can lead to high latency. Likewise, we don’t need to set the maximum length to anything greater than 20 as no individual token will exceed the length of 20. Setting the maximum length to 20 gives us room to spare in case we do eventually ingest an address with a longer token length. Note, the index we are creating here is specifically for autocomplete functionality and is likely unnecessary for a general search index.

PUT custom_index
{
  "mappings": {
    "properties": {
      "text_entry": {
        "type": "text",
        "analyzer": "autocomplete",         
        "search_analyzer": "standard"       
      }
    }
  },
  "settings": {
    "analysis": {
      "filter": {
        "edge_ngram_filter": {
          "type": "edge_ngram",
          "min_gram": 3,
          "max_gram": 20
        }
      },
      "analyzer": {
        "autocomplete": {
          "type": "custom",
          "tokenizer": "standard",
          "filter": [
            "lowercase",
            "edge_ngram_filter"
          ]
        }
      }
    }
  }
}

In the above code, we created an index called custom_index with a custom analyzer named autocomplete. The analyzer performs the following:

  • It uses the standard tokenizer to split text into tokens
  • A lowercase filter is applied to lowercase all the tokens
  • The tokens are then further broken into smaller chunks based off the minimum and maximum values of the edge_ngram

The search analyzer is configured to use the standard analyzer to reduce query processing required at search time. We have already applied our custom analyzer to split the text for us upon ingestion, and we do not need to repeat this process when searching. Test how the custom analyzer analyzes the text Lexington Avenue:

GET custom_index/_analyze
{
  "analyzer": "autocomplete",
  "text": "Lexington Avenue"
}
#========
#Results
#========
# Minimum token length is 3 so we won't see l, or le
    "tokens": 
        "lex"  
        "lexi"  
        "lexin"  
        "lexing" 
        "lexingt" 
        "lexingto"    
        "lexington" 
        "ave"        
        "aven" 
        "avenu" 
        "avenue"

Notice how the tokens are lowercase and now support partial matches. Now that we’ve seen how our analyzer tokenizes our text, bulk add some data:

POST _bulk
{"index":{"_index":"custom_index"}} 
{"text_entry": "123 Amazon Street Seattle, Wa 12345 "} 
{"index":{"_index":"custom_index"}}
{"text_entry": "456 OpenSearch Drive Anytown, Ny 78910"}
{"index":{"_index":"custom_index"}}
{"text_entry": "789 Palm way Ocean Ave, Ca 33345"}
{"index":{"_index":"custom_index"}}
{"text_entry": "987 Openworld Street, Tx 48981"}

And test!

GET custom_index/_search
{
  "query": {
    "match": {
      "text_entry": {
        "query": "ope" 
      }
    }
  }
}
#========
#Results
#========
 "hits": [
      {
        "_index": "custom_index",
        "_id": "aYCEIJgB4vgFQw3LmByc",
        "_score": 0.9733556,
        "_source": {
          "text_entry": "456 OpenSearch Drive Anytown, Ny 78910"
        }
      },
      {
        "_index": "custom_index",
        "_id": "a4CEIJgB4vgFQw3LmByc",
        "_score": 0.4095239,
        "_source": {
          "text_entry": "987 Openworld Street, Tx 48981"
        }
      }
    ]

You have configured a custom n-gram analyzer to find partial words matches within our list of addresses.

Note, there is a tradeoff between using non-standard index analyzers and writing compute intensive queries. Analyzers can affect indexing throughput and increase the overall index size, especially if used inefficiently. For example, when creating the custom_index, the search analyzer was set to use the standard analyzer. Using n_grams for analysis upon ingestion and search would have impacted cluster performance unnecessarily. Additionally, we set the min_gram and max_gram to values that matched our access patterns, ensuring we didn’t create more n_grams than we needed to for our search use case. This allowed us to gain the benefits of optimizing search without impacting our ingestion throughput.

Conclusion

In this post, we changed how OpenSearch indexed our data to simplify and speed up autocomplete queries. In our case, using the Edge n-grams allowed OpenSearch to match parts of an address and yield precise results without compromising cluster performance with a wildcard query.

It’s always important to test your cluster before deploying in a production environment. Understanding your access patterns is essential to optimizing your cluster from both an indexing and searching perspective. Use the guidelines in this post as a starting point. Confirm your access patterns before creating an index, then begin experimenting with different index analyzers in a test environment to see how they can simplify your queries and improve overall cluster performance. For more reading on general OpenSearch cluster optimization techniques, refer to the Get started with Amazon OpenSearch Service: T-shirt-size your domain post.


About the authors

Rakan Kandah

Rakan Kandah

Rakan is a Solutions Architect at AWS. In his free time, Rakan enjoys playing guitar and reading.

Using Amazon SageMaker Unified Studio Identity center (IDC) and IAM-based domains together

Post Syndicated from Praveen Kumar original https://aws.amazon.com/blogs/big-data/using-amazon-sagemaker-unified-studio-identity-center-idc-and-iam-based-domains-together/

Amazon SageMaker Unified Studio now offers two domain configurations: Amazon SageMaker Unified Studio Identity Center(IDC)-based domains with comprehensive governance features, and Amazon SageMaker Unified Studio IAM-based domains with enhanced developer productivity tools.

In this post, we demonstrate how you can use both of these domain configurations of Amazon SageMaker Unified Studio using AWS Identity and Access Management (IAM) role reuse and attribute-based access control.

How authentication works in each configuration

Amazon SageMaker Unified Studio IDC-based domains authenticate users through AWS Identity and Access Management (IAM) Identity Center with Single Sign-On, preserving individual user identities throughout their sessions. These domains excel in governance with identity-based authorization, fine-grained access controls between users, and comprehensive catalog management featuring formal Publisher/Subscriber (Pub/Sub) data sharing workflows with approval processes—ideal for enterprise environments requiring strong identity management, compliance tracking, and identity-based audit trails.

Amazon SageMaker Unified Studio IAM-based domains authenticate through federated AWS Identity and Access Management (IAM) roles where all users accessing a project share the same role permissions. These domains prioritize developer productivity with modern tools including new serverless Notebooks, Athena Spark integration, the improved interface with vertical navigation, and built-in AI assistance, designed for development teams that need streamlined access and advanced analytics capabilities.

This solution facilitates organizations that are already using IDC-based domains to preserve their existing governance frameworks established in IDC-based domains while unlocking modern development capabilities for their teams through IAM-based domains. If you prefer to use the newly launched IAM-based domains, you can continue to do as well. The choice depends on your company’s needs.

Please note that at the time of writing this blog, IAM-based domains do not support Trusted identity propagation. This solution uses the project execution role to configure data access.

The challenge

Imagine a data steward (Sam) uses the IDC-based domain to define data access policies, manage the data catalog, and approve subscription requests to verify compliance and proper data governance.

On the other hand, a data engineer (Sarah), wants to use IDC-based domain for governance features such as SageMaker catalog and IAM-based domain for the new serverless Notebook to build data pipelines, perform advanced analytics, and accelerate development cycles. Sarah will request access to the data through IDC-based domain, and once access is approved by Sam, Sarah can access this data in serverless notebook available in IAM-based domain.

Solution overview

The integration leverages IAM role reuse, AWS Lake Formation Attribute-Based Access Control (ABAC) and Amazon SageMaker Catalog pub-sub model to automatically carry permissions from the IDC-based domain to the new IAM-based domain. When properly configured, data subscriptions managed through the IDC-based domain’s Pub/Sub model become immediately accessible in IAM-based domain projects, providing a unified data access experience.

The solution we will implement in the post involves creating an IAM-based domain project that is similar to your IDC consumer project (eg same team members, use case) , configuring execution roles, and enabling role reuse. This approach maintains the familiar subscription workflow while extending benefits to the IAM-based domain.The following diagram shows the high-level architecture of how this approach works.

AWS SageMaker data governance workflow diagram showing data engineer Sarah performing data discovery and exploration through SageMaker IDC and IAM domains, with data steward and owner Sam managing approvals via Business Data Catalog, connecting to Polyglot AI Notebook and SQL tools.

The solution architecture consists of:

  • Existing IDC-based domain: Contains producer and consumer projects with established data sharing via Pub/Sub model
  • IAM-based domain: New projects with federated and execution roles configured for modern development tools
  • IAM Identity Center: Manages federated access and permission sets
  • Attribute-Based Access Control: Tags on execution roles enable automatic permission inheritance

The solution provides 2 options: Option 1: IDC-Based Domain project role reuse provides the simplest integration path by directly reusing the existing consumer project IAM role from your IDC-based domain as the execution role in the IAM-based domain. The primary benefits include simplified setup requiring only policy changes (covered later in the blog), reduced administrative overhead with one less role to manage and lower risk of misconfiguration since you’re leveraging proven, existing roles. Choose Option 1 when you want the fastest implementation path, your organization prefers minimal role proliferation, you have well-established IDC-based domain roles that already have data access permissions, or your team has limited IAM expertise and wants to avoid complex tagging configurations.

Option 2: Creating a new execution role for the IAM-based domain project and use attribute-based access control (ABAC) through tagging with the IDC-based domain project ID. The key benefits include enhanced auditability with two distinct roles (one for IDC-based domain, one for IAM-based domain), clear separation showing which domain generated each request in CloudTrail logs, greater flexibility to customize permissions specific to IAM-based domain needs without affecting IDC-based domain operations, and better security isolation between the two domain types. The `AmazonDatazoneProject` tag enables attribute based access control, while maintaining distinct role identities. Choose Option 2 when: your organization requires detailed audit trails distinguishing between domain types, compliance policies mandate separation of concerns between governance and development environments, you want to track and attribute costs separately for each domain, or you need to provide evidence showing which domain (governance vs. development) accessed specific data resources for compliance reporting.

Here is the high-level view of how the identity and domain entities map to each other for both options:

AWS IAM Identity Center integration with Amazon SageMaker diagram showing access flow from IdC Groups through Permission Sets to AWS SSO IAM Roles, connecting to SageMaker domains with two implementation options: Option 1 using identical IAM roles, or Option 2 using project-tagged execution roles

Prerequisites

To follow along with this post, you should have:

For this demonstration, we use a simplified setup with a sales producer project and a marketing consumer project that subscribes to these tables.

Understanding the current IDC-based domain setup

Our starting point includes a well-established Amazon SageMaker Unified Studio IDC-based domain structure:

Sales Producer Project

  • Contains a database with pipeline and sales tables
  • Managed by Sam, the data steward who creates and publishes data assets
  • Has its own project IAM role

Marketing Consumer Project

  • Managed by Sarah, the data engineer who subscribes to published data via IDC domain project
  • Has its own project IAM role
  • Successfully queries subscribed data through the IDC-based domain interface

Each project has an associated IAM role that governs access to data assets, and the Pub/Sub model manages subscription workflows and permissions.

Setting up federated role through permission sets

Federated roles through permission sets are used to authenticate and provide users with console access to IAM-based domains through AWS IAM Identity Center, where all users within a project share the same role permissions. When you assign a permission set, IAM Identity Center creates corresponding IAM Identity Center-controlled IAM role in AWS account, and attaches the policies specified in the permission set to that role.

IAM-based SMUS domains enable streamlined access to modern development tools (serverless Notebooks, Athena Spark, AI assistance) while maintaining governance, automatically propagating permissions across domains without requiring duplicate access approvals, and simplifying team member onboarding.You can use any IAM role to access IAM-based domain. For this post, we will use federated role option using AWS IAM Identity Center (IDC).

Grant access to Data engineer group for IAM-based domains in Identity Center

1) Set up federated role in AWS IAM Identity Center

Navigate to IAM Identity Center (IDC) in the AWS Management Console, then complete the following steps:

  1. Go to permission set section in IDC. Create a new permission set called Marketing-federated-role and select Attach Policy.

AWS IAM Identity Center console screenshot displaying the marketing-federated-role permission set configuration page with provisioned status, 1-hour session duration, and empty AWS managed and customer managed policy sections with attach policy options.

  1. Search for SageMakerStudioUserIAMConsolePolicy in the existing policy name from list and select SageMakerStudioUserIAMConsolePolicy from the list. Note that the managed policy SageMakerStudioUserIAMConsolePolicy must be attached or have the same permissions added via another policy to be able to access projects in a SageMaker IAM domain.

AWS IAM Identity Center console screenshot showing AWS managed policies section with one attached SageMakerStudioUserIAMConsolePolicy and empty customer managed policies section with detach and attach policy options available.

  1. Go to the AWS account section of IDC.
  2. Assign the created permission set to your AWS account.

AWS IAM Identity Center console screenshot showing AWS accounts page in hierarchy view with organization o-9svtz1aavh, displaying Root organizational unit containing AWS account n.com with marketing-federated-role permission set assigned and assign users or groups option.

  1. For this post we assigned the permission set to marketing group, As a best practice, you should setup and grant access to groups rather than individual users.

AWS IAM Identity Center console screenshot showing marketing group details page with AWS accounts tab selected, displaying one AWS account access (management account amazon.com) with marketing-federated-role permission set applied.

  1. Add Sarah to marketing group.

AWS IAM Identity Center console screenshot showing marketing group's Users tab with one enabled member (user sarah, Display name: Sarah M) who inherits permissions to AWS accounts and Identity Center enabled applications.

This creates a federated role that Sarah can use to access the IAM-based domain. The federated role appears as an IAM role within your account and serves as the entry point for console access.

Setting up IAM-based domain execution role

There are 2 options to setup execution role for IAM-based domain project. The execution role has a one-to-one mapping with the federated role.

Option 1 – IDC-based domain Project Role reuse

Instead of creating a new execution role and tagging it, you can configure the IAM-based domain project to directly reuse the consumer project IAM role from the IDC-based domain as the execution role. This option only needs policy changes to the consumer project IAM role. To find the IDC-based domain consumer project IAM role:

  1. Navigate to the Amazon SageMaker Unified Studio IDC-based domain portal.
  2. Open the Marketing Consumer Project.
  3. Copy the project role ARN from the project overview page.

Amazon DataZone project overview page displaying marketing-project details with active status, project ID 4tcycvm4c684rt, domain ID dzd-47supbt0i3jysp, All capabilities profile, Corp domain unit, Amazon S3 location in us-east-2, and project role ARN with up-to-date status.

  1. You will need to modify this execution role’s policy with detailed instructions provided later in the blog.

Setting up IAM-based domain project for option 1

To create an IAM-based domain project that will integrate with your existing IDC-based domain permissions, complete the following steps:

  1. Log in to the AWS Console using IAM-based domain administrator.
  2. Navigate to Amazon SageMaker page within console.
  3. Choose Open.

Amazon SageMaker landing page displaying "The center for data, analytics, and AI" with tagline about next-generation integrated analytics experience, serverless notebooks with built-in AI Agent, Amazon DataZone integration note, and call-to-action panel featuring "Get started with Amazon SageMaker Unified Studio" with Open button and View existing domains

  1. Once logged in to IAM-based domain as admin, choose Manage projects.

Amazon SageMaker admin-project dashboard displaying left navigation menu with data analytics and AI/ML sections, quick-start cards for exploring data, building in notebooks, and discovering ML models, plus four sample data project templates: Customer usage analysis (3 mins), Customer segmentation (8 mins), Customer churn prediction (5 mins), and Retail sales forecasting (20 mins).

  1. Next, click on Create Project.

Amazon DataZone Domain Administration Projects page showing "Projects (3)" with description about enabling IAM role-based access to AWS Analytics and AI/ML tools, search functionality to find projects, last refreshed timestamp, and green Create project button.

  1. Enter project name as “Marketing Consumer Project”.

Amazon DataZone Create project dialog showing Step 1 "Enter Details" with required Project name field containing "Marketing Consumer Project" (1-64 characters, a-z, A-Z, 0-9, spaces, dashes, underscores allowed) and optional Description field with 0/2048 character count, followed by Step 2 "Assign roles".

  1. During project creation, select the following crucial roles and then choose Create Project:
  • Project IAM Role: The marketing federated role created in IAM Identity Center above. This is the role in the member account that has a role name with suffix AWSReservedSSO.
  • Project Role: – Choose project role for data engineer, copied from option 1.

Amazon SageMaker Unified Studio Create project dialog showing IAM role configuration with AWSReservedSSO_marketing-federated-role selected, blue alert requiring SageMakerStudioUserIAMConsolePolicy attachment, Execution role section with "Use an existing role" option selected, and datazone_usr_role_4tcycvm4c684rt_ajtckkwo2fnhyh IAM role specified with note that role is not editable after project creation

  1. Make policy changes to this project role as per the instruction on the SMUS UI page.

Amazon SageMaker Unified Studio role selection interface showing "Use an existing role" option selected with IAM role datazone_usr_role_4tcycvm4c684rt_ajtckkwo2fnhyh, blue information box displaying required permissions including SageMakerStudioUserIAMDefaultExecutionPolicy managed policy, trust policy enabling Amazon SageMaker Unified Studio service assumption, and inline policy for role pass-through, with note that role is not editable after project creation.

Option 2 – Bring your own execution role. 

To create an IAM-based domain project that will integrate with your existing IDC-based domain permissions., you must tag the execution role for permission propagation. Amazon SageMaker Catalog and AWS Lake Formation use attribute-based access control, which means permissions can be inherited based on resource tags. For this option, you will need consumer project ID.To find the IDC-based domain consumer project ID:

  1. Navigate to the Amazon SageMaker Unified Studio IDC-based domain portal.
  2. Open the Marketing Consumer Project.
  3. Copy the project ID from the project details.

Amazon SageMaker Unified Studio marketing-project overview page displaying navigation breadcrumb (Home > Projects > marketing-project > Project overview), left sidebar menu with Project overview, Data, Compute, Members, and Project catalog sections, Project files section listing 3 JupyterLab files (.libs.json, README.md, getting_started.ipynb) last modified November 18, 2025, Readme section with Welcome heading describing SageMaker Unified Studio, and Project details tab showing project name, ID, last modified date November 21, 2025, and Amazon S3 location.” width=”2196″ height=”1164″></p>
<h3>Setting up IAM-based domain project for option 2</h3>
<p>Complete the following steps:</p>
<ol>
<li>Create another project with name “Marketing Consumer Project 2” in the IAM-based domain while logged in as admin.</li>
<li>During project creation, select the following roles:
<ol type=

  • Federated Role: The marketing federated role created in IAM Identity Center above.
  • Execution Role: – Choose execution role from option 2.
  • Make policy changes to this execution role as per the instruction.
  • Amazon SageMaker Unified Studio role selection interface showing "Use an existing role" option selected with IAM role field containing "sagemaker-marketing-execution-role", blue information box displaying required permissions including SageMakerStudioUserIAMDefaultExecutionPolicy managed policy, trust policy enabling Amazon SageMaker Unified Studio and related services to assume the role, and inline policy allowing role pass-through to other services, with note that role is not editable after project creation

    1. Next, navigate to the IAM console and locate the execution role created for your IAM-based domain consumer project.
    2. Add the following tag, this step relies on ABAC policies with projectId for subscriptions.
    • Key: AmazonDatazoneProject
    • Value: The project ID from your Amazon SageMaker Unified Studio IDC-based domain consumer project

    AWS IAM console displaying sagemaker-marketing-execution-role details page with Summary section showing creation date November 18, 2025, last activity 3 days ago, ARN arn:aws:iam::role/sagemaker-marketing-execution-role, 1-hour maximum session duration, five tabs (Permissions, Trust relationships, Tags (1), Last Accessed, Revoke sessions), and Tags section displaying one tag with Key "AmazonDataZoneProject" and Value "4tcycvm4c684rt" with Delete, Edit, and Manage tags buttons available.

    This tag configuration results in data access grant from IDC-based domain consumer project to the IAM-based domain project execution role.

    Verify data access in the IAM-based domain

    After tagging the execution role, verify that permissions are set up correctly.Complete the following steps:

    1. Use the SSO URL to log into the SSO Identity Center as Sarah.

    AWS IAM Identity Center Dashboard displaying left navigation menu with Dashboard, Users, Groups, Settings, Multi-account permissions (AWS accounts, Permission sets), and Application assignments sections; central management panel showing service control policies guidance with yellow warning banner about member account instances and CloudTrail monitoring section; IAM Identity Center setup area with three action cards for confirming identity source, managing multi-account permissions, and setting up application assignments; right panel Settings summary showing Identity Center directory as identity source, us-east-2 region, organization ID o-9svtz1aavh, AWS access portal URL, and issuer URL; What's new section highlighting customer-managed KMS keys support and Amazon SageMaker Studio user background sessions; Related consoles links to CloudTrail, AWS Organizations, and IAM.

    1. Open the AWS console using federated role created earlier in setting federated role section.
    2. Navigate to Amazon SageMaker.
    3. Choose Amazon SageMaker Unified Studio IAM-based domain option (this will show up if project is already created with federated role).

    Amazon SageMaker Unified Studio marketing-project dashboard displaying left navigation menu with Overview, Files, Data, Connections, Code (Notebooks, JupyterLab), Data analytics (Query Editor, Visual ETL, Data processing jobs), and AI/ML sections (Models, MLflow, Training jobs, Inference endpoints); main content area showing "Jump into your data and models" with three quick-start cards (Explore your data, Build in the notebook, Discover ML models) and four sample data projects: Retail sales forecasting (20 mins), Customer churn prediction (5 mins), Customer segmentation (8 mins), and Customer usage analysis (3 mins); top-right panel displaying account details with us-east-2 region, federated user aws-reserved/sarah, and execution role sagemaker-marketing-execution-role.

    1. In the Amazon SageMaker Unified Studio IAM-based domain project, navigate to the Data tab. If you created 2 projects with both option 1 and option 2 execution role, then 2 projects will show up and you can login to either to validate data access.

    Amazon SageMaker Unified Studio data explorer interface displaying SQL query "SELECT * FROM glue_db_6doxdp1wuy165l.sales_table LIMIT 100" executed via Athena in 6 seconds, showing six columns (ord_num, sales_qty_sld, wholesale_cost, lst_pr, sell_pr, disnt) with green distribution histograms above data preview table containing six sample sales records with order numbers ranging from 46776931 to 146776932, left navigation showing AwsDataCatalog database structure with glue_db_6doxdp1wuy165l containing pipeline_table and sales_table, last saved 2 minutes ago.

    1. Verify that the consumer database and subscribed tables appear.

    Create and use the new serverless notebooks

    With permissions properly configured, you can now use IAM-based domain capabilities like serverless Notebooks. Complete the following steps:

    1. In the Amazon SageMaker Unified Studio IAM-based domain project, select a table from the Data tab.
    2. Choose Create notebook.
    3. The Notebook opens with Athena SQL as the default cell type.
    4. Write and run queries against your subscribed data.

    Amazon SageMaker Unified Studio marketing-project notebook displaying sales_table data from 2025-11-18 21:42:01, left Data explorer showing AwsDataCatalog with glue_db_6doxdp1wuyi65l database containing pipeline_table and sales_table, main data table showing 11 rows with columns (ord_num, sales_qty_sld, wholesale_cost, lst_pr, sell_pr, disnt) displaying rows 4-9 on page 1 of 2, Python PySpark SQL query "SELECT * FROM 'glue_db_6doxdp1wuyi65l'.'pipeline_table' LIMIT 100" executed in 27 seconds, and Filters section displaying distribution histograms for all numerical columns.

    The notebook runs with the execution role’s permissions, which now include access to all data subscribed through the IDC-based domain.

    Key benefits of this integration

    This integration approach delivers several important advantages:

    Preserve existing investments

    • Continue using IDC-based domain governance and catalogs.
    • Maintain established Pub/Sub workflows.
    • No migration required for existing data assets.

    Get modern capabilities

    • Provide developers with the new serverless Notebooks.
    • Access Athena Spark for advanced analytics.
    • Provides improved user experience and navigation.

    Simplified permission management

    • Single subscription workflow manages access across both domains.
    • Consistent data access via role reuse and attribute-based access control.
    • No duplicate access requests or approvals needed.

    Unified data experience

    • Developers access all subscribed data from one interface.
    • Consistent data catalog across domains.
    • Simplified onboarding for new team members.

    Cleanup

    Complete the following steps to delete the resources you created:

    1. Delete the serverless Notebooks created in the IAM-based domain projects.
    2. Delete the IAM-based domain projects (Marketing Consumer Project and Marketing Consumer Project 2).
    3. Remove the permission set assignment from marketing group in IAM Identity Center.
    4. Delete the Marketing-federated-role permission set in IAM Identity Center.
    5. Remove the tags (AmazonDatazoneProject) from the execution role (if using Option 2).
    6. Delete the execution role created for the IAM-based domain (if using Option 2 and not reusing the IDC-based domain project role).
    7. Revert any policy changes made to the IDC-based domain consumer project IAM role (if using Option 1).
    8. If you do not need the IAM-based domain anymore, delete it.
    9. If you created any test data subscriptions in the IDC-based domain, remove them.

    Conclusion

    In this post, we demonstrated how to access Amazon SageMaker Unified Studio IDC-based domain with the new IAM-based domain using role reuse and attribute-based access control. This setup offers data engineers the best of both worlds: access to specialized modern development tools—including the new serverless Notebooks, Athena Spark integration, and built-in AI assistance , while maintaining proper governance that includes comprehensive catalog management and robust security controls established in the IDC-based domain.You can now confidently adopt Amazon SageMaker Unified Studio IAM-based domain capabilities knowing their established data governance, subscription workflows, and access controls remain intact and continue to function as expected.

    Ready to get started with Amazon SageMaker Unified Studio and unlock the power of integrated governance and modern development tools for your organization? Visit the Amazon SageMaker Unified Studio documentation to learn more and begin your implementation today.


    About the authors

    Praveen Kumar

    Praveen Kumar

    Praveen is a Principal Analytics Solutions Architect at AWS with expertise in designing, building, and implementing modern data and analytics platforms using cloud-based services. His areas of interest are serverless technology, data governance, and data-driven AI applications.

    Durga Mishra

    Durga Mishra

    Durga is a Principal Data and AI solutions architecture strategist at AWS . Outside of work, Durga enjoys building new things and spending time with family. He loves to hike on Appalachian trails and spend time in nature.

    Joel

    Joel Farvault

    Joel is a Principal Specialist SA Analytics for AWS with 25 years’ experience working on enterprise architecture, data governance and analytics. He uses his experience to advise customers on their data strategy and technology foundations.

    author name

    Satish Sarapuri

    Satish is a Sr. Data Architect for Data Mesh/Data Lake/Gen AI at AWS. He helps enterprise-level customers build generative AI, data mesh, data lake, and analytics platform solutions on AWS to help them make data-driven decisions and gain impactful outcomes for their business. In his spare time, he enjoys trail running and spending quality time with his family.

    author name

    Leonardo Gomez

    Leonardo is a Principal Analytics Specialist Solutions Architect at AWS. He has over a decade of experience in data management, helping customers around the globe address their business and technical needs.

    How Convera built fine-grained API authorization with Amazon Verified Permissions

    Post Syndicated from Santhosh Veeraraman original https://aws.amazon.com/blogs/architecture/how-convera-built-fine-grained-api-authorization-with-amazon-verified-permissions/

    Convera processes billions in cross-border payment volume yearly for businesses and financial institutions worldwide. As their platform grew, they needed a robust authorization system that could protect sensitive financial data while maintaining operational efficiency across their global network.

    In this post, we share how Convera used Amazon Verified Permissions to build a fine-grained authorization model for their API platform.

    Background

    As Convera’s service offerings expanded, they needed a scalable, secure, and auditable way to enforce role-based and attribute-based access control. Their goal was to make sure users, both internal and external, had access only to the resources and actions they were explicitly authorized for, while maintaining flexibility to adapt to evolving business needs. Initially, Convera explored building an in-house access control solution. However, they realized that implementing policy management, real-time authorization, logging, and auditing from scratch would require significant engineering effort and ongoing maintenance, diverting resources from their core business priorities. Convera chose Verified Permissions for implementing fine-grained authorization for their payment APIs. This choice was driven by the following factors:

    • Direct integration with AWS services like Amazon Cognito and Amazon API Gateway
    • Cedar policy language’s flexibility in defining complex authorization rules
    • Ability to evaluate multiple attributes like user roles, transaction amounts, and geographic locations
    • High-performance characteristics with millisecond-level authorization decisions

    Given its flexibility and scalability, Verified Permissions became the foundational reference architecture for managing access control across two main scenarios:

    • Fine-grained access control – Convera’s Payment platform serves diverse users including customers, internal staff, and machine-to-machine communications, each requiring specific entitlements based on their roles, organizational hierarchy, and context.
    • Multi-tenancy controls – One of Convera’s most complex requirements was enabling multi-tenant access control while enforcing strict data isolation. Verified Permissions make it possible to define policies that dynamically evaluated tenant ownership, user roles, and contextual attributes.

    The following analysis breaks down Convera’s implementation approach across their major use cases

    Fine-grained access control

    Fine-grained access control is a critical aspect of application security that makes sure users have precisely defined permissions, granting access only to specific resources or actions within an application. Using Verified Permissions, you can define a schema in terms of entity type, including attributes relevant to the authorization model and the valid combinations of principal types, resource types, and actions. Verified Permissions uses this schema to validate that a static policy or policy template is consistent with the application’s authorization model.

    Convera implemented Verified Permissions for fine-grained access control across multiple user types and interaction patterns.

    Customer access management

    At the UI level, Convera used Verified Permissions to manage API access based on specific user characteristics. For example, in their financial applications, the visibility of transaction features like the modify payment parameters is dynamically controlled based on Verified Permissions policies.

    The following diagram illustrates the user authentication decision flow for financial transactions.

    User Authorization Decision for financial transactions

    Figure 1: User Authorization Decision for financial transactions

    The following is an example Cedar policy that can be used in conjunction with Verified Permissions to achieve this use case. This policy makes sure only authorized users with specific roles can see sensitive financial controls. The same policy must be evaluated at the API level when the actual transfer request is made. At the service level, the policy is designed to provide fine-grained access controls.

    permit (
        principal,
        action in [MyApp::Action::"ViewTransferButton"],
        resource
    ) when {
        principal.role == "PAYMENT_INITIATOR" &&
        resource.accountType == "BUSINESS" &&
        resource.status == "ACTIVE"     
    };

    You can integrate the application with Verified Permissions through the API to authorize user access requests. For each authorization request, the service retrieves the relevant policies and evaluates those policies to determine whether a user is permitted to take an action on a resource given context input such as users, roles, group membership, and attributes.

    The following figure illustrates the end-to-end architectural diagram of this implementation.

    Fine-grained User Authorization control with Verified PermissionsPermissions

    Figure 2: Fine-grained User Authorization control with Verified Permissions

    The workflow consists of the following steps:

    1. Users initiate login through the client application.
    2. The client authenticates with Amazon Cognito.
    3. Amazon Cognito triggers a pre-token generation AWS Lambda function to get user roles.
    4. The Lambda function fetches user roles from Amazon Relational Database Service (Amazon RDS).
    5. The Lambda function enriches a JSON Web Token (JWT) with user role information.
    6. The enriched JWT with user roles is returned to the client application.
    7. The client application makes an API call, sending an authorization request to API Gateway through the enriched JWT.
    8. A Lambda authorizer validates the JWT and the role permissions from the JWT and makes a call to Verified Permissions.
    9. Verified Permissions reads access policies stored as Cedar policies and makes an authorization decision.
    10. Verified Permissions returns the authorization result to the Lambda authorizer.
    11. The Lambda authorizer, based on the authorization result, sends an AWS Identity and Access Management (IAM) policy that allows or denies the request to API Gateway.
    12. API Gateway either allows or denies the request to the client application.
    13. API Gateway caches the IAM policy.

    The policy governance is owned by Convera’s infosec team through a strictly regulated IAM role. The changes to the Cedar policies are captured using Amazon DynamoDB Streams and continuously synced with Verified Permissions.

    To improve speed, Convera created a two-level cache system, using the API Gateway built-in cache for authorization decisions and application-level caching for Amazon Cognito tokens. The Lambda function invokes Verified Permissions to authorize the request. If Verified Permissions returns deny, the request is rejected, and an HTTP unauthorized response (403) is sent back. If Verified Permissions returns allow, the request is moved forward. This multi-level caching approach successfully delivers sub-millisecond response times while reducing operational costs and maintaining security controls.

    Internal customer connect applications

    Convera was able to reuse the same architecture for their internal user access as well, such as customer service associates who need quick access to client information to provide efficient service while protecting access to sensitive data. Using Verified Permissions, a role-specific Cedar policy was created to achieve the following:

    • Enable view-only access to basic customer profiles, including contact information and service history
    • Restrict edit capabilities to specific fields, such as updating contact preferences or logging support interactions
    • Block access to sensitive financial data or internal business metrics

    In this flow, internal users authenticate through their enterprise identity provider (IdP), in this case Okta, through the Convera Connect App and obtain ID and access tokens from Amazon Cognito. Amazon Cognito, using a pre-token generation hook, customizes the access token with user attributes stored in Amazon DynamoDB. Although the Cedar policies are tailored for internal roles and responsibilities (different from customer-facing policies), the fundamental flow involving API Gateway, a Lambda authorizer, Verified Permissions policy evaluation, and decision caching remains identical. This architectural reuse meant Convera didn’t need to rebuild their authorization infrastructure, so they can use the same performance optimizations, security controls, and operational processes across both customer and internal user access patterns.

    Extending the model to service communication

    After successfully implementing Verified Permissions for customer and internal user access control, Convera recognized they could use the same architecture for securing service-to-service communications. Similar to how they manage user authentication through Amazon Cognito user pools, each client service is registered in their client configuration system, with Verified Permissions creating a dedicated policy store for service-specific permissions. Services authenticate through Amazon Cognito using client credentials (instead of user credentials) to obtain access tokens that carry service-specific attributes such as service identifier, tier, allowed operations, and rate limits.

    The following diagram illustrates the machine-to-machine architecture for internal and external partner integration.

    Machine to machine architecture for internal and external partner integration

    Figure 3: Machine to machine architecture for internal and external partner integration

    The workflow consists of the following steps:

    1. Service A sends an API request to the authentication token endpoint in API Gateway, including its access token.
    2. The request is forwarded to Amazon Cognito, which validates the token from the machine-to-machine user pool.
    3. Service A, now authenticated, makes a request to the business API (Service B) through API Gateway.
    4. API Gateway forwards the request to the Lambda authorizer, which processes the incoming request and extracts the service context from the token.
    5. The Lambda authorizer sends the authorization request to Verified Permissions to evaluate it against stored Cedar policies. The evaluation considers:
      1. Service identity
      2. Requested operation
      3. Resource context
      4. Environmental factors
    6. Verified Permissions returns an allow or deny decision. If allowed:
      1. The Lambda authorizer generates an appropriate IAM policy.
      2. API Gateway caches the authorization decision.
      3. The request is forwarded to Service B.
      4. Future similar requests can use the cached decision.

    Multi-tenancy controls

    As Convera expanded to support multi-tenant software as a service (SaaS) integrations, they needed a way to implement tenant-specific access controls and data isolation. The challenge was to make sure each tenant’s users could only access their authorized resources while allowing tenant administrators to manage their own access policies. Convera used their existing Verified Permissions architecture with a per-tenant policy store approach to address these requirements.

    Verified Permissions per-tenant policy store

    Convera decided to use per-tenant policy store approach for the following reasons:

    • Low-effort tenant policies isolation
    • The ability to customize templates and schema per tenant
    • Low-effort tenant onboarding and offboarding
    • Per-tenant policy store resource quotas

    The following figure shows the process of implementing fine-grained authorization control using Verified Permissions with a per-tenant policy store.

    Fine-grained authorization control using Verified Permissions with per-tenant policy store

    Figure 4: Fine-grained authorization control using Verified Permissions with per-tenant policy store

    The end-to-end process flow consists of the following steps:

    1. The tenant-specific Amazon Cognito pool is created with a custom attribute called tenant_id. The user logs in to the pool with user claims (for example, user_id).
    2. Amazon Cognito uses a pre-token generation Lambda function that looks up the user_id from a user tenant mapping DynamoDB table.
    3. A DynamoDB table is maintained to map user and tenant configuration.
    4. The pre-token generation Lambda hook gets the tenant_id back from DynamoDB, and adds to the custom tenant_id attribute in the access token.
    5. The user makes an API call to API Gateway with the enriched JWT.
    6. API Gateway validates the token and forwards the request to a custom Lambda authorizer.
    7. The Lambda authorizer function reads the tenant_id from the JWT and looks up the associated Verified Permissions policy-store-id from a DynamoDB table.
    8. The Lambda authorizer verifies the JWT for validity and claims with the Verified Permissions associated Amazon Cognito pool taken from the access token.
    9. If authentication is successful, it calls Verified Permissions to verify that the user is permitted to do the requested action.
    10. If allowed, Verified Permissions returns an IAM policy with Allow access (Deny-by-Default) and forwards the request to backend Kubernetes pods with tenant_id in a custom header.
    11. Backend services receive the tenant_id and validate with Verified Permissions again (for zero-trust policy), creates a tenant context, and forwards to Amazon RDS. Amazon RDS is configured to accept only requests with specific tenant context and returns data specific to the requested tenant_id.

    The following are some examples of Cedar policies used for multi-tenant isolation:

    permit (
        principal in
            convera_connect_authz::userGroup::"ConveraConnect-PAYEE_MGMT",
        action in [convera_connect_authz::Action::"PUT /customer/user/{id}"],
        resource
    );
     
    permit (
        principal,
        action in [convera_connect_authz::Action::"EDIT"],
        resource
    )
    when
    {
        principal.role.contains("UPDATE_USER_STATUS") &&
        resource.type == "PUT" &&
        resource.path == "/customers/user"
    };

    Conclusion

    In this post, we explored how Convera used Verified Permissions to build a sophisticated, fine-grained authorization model for their API platform. We discussed about how Convera was able to implement fine-grained access for their customers, multi-tenant SaaS integrations, machine-to-machine communication scenarios, and internal customer connect applications with the help of Verified Permissions. With Verified Permissions, Convera was able to achieve the following:

    • Implement fine-grained access control across multiple use cases
    • Enhance security with attribute-based access control across multi-tenant environments
    • Improve scalability, handling over thousands of authorization requests per second with submillisecond latency.
    • Increase operational efficiency, reducing time spent on access management tasks by 60%.
    • Future-proof their authorization framework to adapt to evolving business needs

    To learn more about implementing these patterns and best practices, refer to the Verified Permissions User Guide. For hands-on experience, we recommend exploring the Verified Permissions workshop, which provides practical examples and guided exercises.


    About the authors

    Reduce Mean Time to Resolution with an observability agent

    Post Syndicated from Muthu Pitchaimani original https://aws.amazon.com/blogs/big-data/reduce-mean-time-to-resolution-with-an-observability-agent/

    Customers of all sizes have been successfully using Amazon OpenSearch Service to power their observability workflows and gain visibility into their applications and infrastructure. During incident investigation, Site Reliability Engineers (SREs) and operations center personnel rely on OpenSearch Service to query logs, examine visualizations, analyze patterns, correlate traces to find the root cause of the incident, and reduce Mean Time to Resolution (MTTR). When an incident happens that triggers alerts, SREs typically jump between multiple dashboards, write specific queries, check recent deployments, and correlate between logs and traces to piece together a timeline of events. Not only is this process largely manual, but it also creates a cognitive load on these personnel, even when all the data is readily available. This is where agentic AI can help, by being an intelligent assistant that can understand how to query, interpret various telemetry signals, and systematically investigate an incident.

    In this post, we present an observability agent using OpenSearch Service and Amazon Bedrock AgentCore that can help surface root cause and get insights faster, handle multiple query-correlation cycles, and ultimately reduce MTTR even further.

    Solution overview

    The following diagram shows the overall architecture for the observability agent.

    Applications and infrastructure emit telemetry signals in the form of logs, traces, and metrics. These signals are then gathered by OpenTelemetry Collector (Step 1) and exported to Amazon OpenSearch Ingestion using individual pipelines for every signal: logs, traces, and metrics (Step 2). These pipelines deliver the signal data to an OpenSearch Service domain and Amazon Managed Service for Prometheus (Step 3).

    OpenTelemetry is the standard for instrumentation, and provides vendor-neutral data collection across a broad range of languages and frameworks. Enterprises of various sizes are adopting this architecture pattern using OpenTelemetry for their observability needs, especially those committed to open source tools. More notably, this architecture builds on open source foundations, helping enterprises avoid vendor lock-in, benefit from the open source community, and implement it across on-premises and various cloud environments.

    For this post, we use the OpenTelemetry Demo application to demonstrate our observability use case. This is an ecommerce application powered by about 20 different microservices, and generates realistic telemetry data together with feature sets to generate load and simulate failures.

    Model Context Protocol servers for observability signal data

    The Model Context Protocol (MCP) provides a standardized mechanism to connect agents to external data sources and tools. In this solution, we built three distinct MCP servers, one for each type of signal.

    The Logs MCP server exposes tool functions for searching, filtering, and selecting log data that is stored in an OpenSearch Service domain for log data. This enables the agent to query the logs using various criteria like simple keyword matching, service name filter, log level, or time ranges. This mimics the typical queries you would run during an investigation. The following snippet shows a pseudo code of what the tool function can look like:

    # Logs MCP Server - Key Functions
    search_otel_logs(
        query: string,           # Text search query for log messages
        service: string,         # Service name to filter logs
        severity: string,        # Log level (INFO, WARN, ERROR)
        startTime: string,       # Start time (ISO format or relative e.g., 'now-1h')
        endTime: string,         # End time (ISO format or relative e.g., 'now')
        size: number             # Number of results to return
    )
    get_logs_by_trace_id(
        traceId: string,         # Trace ID to retrieve all correlated logs
        size: number             # Maximum number of logs to return
    )

    The Traces MCP server exposes tool functions for searching and retrieving information about distributed traces. These functions can help look up traces by trace ID and find traces for a particular service, the spans belonging to a trace, the service map information constructed based on the spans, and the rate, error, and duration (also known as RED metrics). This enables the agent to follow a request’s path across the services and pinpoint where failures happened or latency originated.

    # Traces MCP Server - Key Functions
    get_otel_spans(
        serviceName: string,     # Service name to filter spans
        traceId: string,         # Trace ID to filter spans
        spanId: string,          # Span ID to retrieve a specific span
        operationName: string,   # Operation/span name to filter
        startTime: string,       # Start time (ISO format or relative)
        endTime: string,         # End time (ISO format or relative)
        size: number             # Number of results to return
    )
    get_spans_by_trace_id(
        traceId: string,         # Trace ID to retrieve all spans for
        size: number             # Maximum number of spans to return
    )
    get_otel_service_map(
        serviceName: string,     # Service name to filter service map
        startTime: string,       # Start time
        endTime: string,         # End time
        size: number             # Number of results to return
    )
    get_otel_rate_error_duration_metrics(
        startTime: string,       # Start time (default: 'now-5m')
        endTime: string          # End time (default: 'now')
    )

    The Metrics MCP server exposes tool functions for querying time series metrics. The agent can use these functions to check error rate percentiles and resource utilization, which are key signals for understanding the overall health of the system and identifying anomalous behavior.

    # Metrics MCP Server - Key Functions
    query_instant(
        query: string,           # PromQL query expression
        time: string,            # Evaluation timestamp (optional)
        timeout: string          # Evaluation timeout (optional)
    )
    query_range(
        query: string,           # PromQL query expression
        start: string,           # Start timestamp
        end: string,             # End timestamp
        step: string,            # Query resolution step (e.g., '15s', '1m')
        timeout: string          # Evaluation timeout (optional)
    )
    get_timeseries(
        metric: string,          # Metric name or PromQL expression
        duration: string,        # Time duration to look back (e.g., '1h', '6h')
        step: string             # Step size (optional)
    )
    search_metrics(
        pattern: string          # Search pattern (supports regex e.g., 'http.*')
    )
    explore_metric(
        metric: string           # Metric name to explore (metadata + samples)
    )

    These three MCP servers span across the different types of data used by investigation engineers, providing a complete working set for an agent to conduct investigations with autonomous correlation across logs, traces, and metrics to determine the possible root causes for an issue. Additionally, a custom MCP server exposes tool functions over business data on revenue, sales, and other business metrics. For the OpenTelemetry demo application, you can develop synthetic data to aid in providing context for impact and other business level metrics. For brevity, we don’t show that server as a part of this architecture.

    Observability agent

    The observability agent is central to the solution. It is built to help with incident investigation. Traditional automations and manual runbooks typically follow predefined operating procedures, but with an observability agent, you don’t need to define them. The agent can analyze, reason based on the data available to it, and adapt its strategy based on what it discovers. It correlates findings across logs, traces, and metrics to arrive at a root cause.

    The observability agent is built with the Strands Agent SDK, an open source framework that simplifies development of AI agents. The SDK provides a model-driven approach with flexibility to handle underlying orchestration and reasoning (the agent loop) by invoking exposed tools and maintaining coherent, turn-based interactions. This implementation also discovers tools dynamically, so if there is a change in the capabilities, the agent can make decisions based on up-to-date information.

    The agent runs on Amazon Bedrock AgentCore Runtime, which provides fully managed infrastructure for hosting and running agents. The runtime supports popular agent frameworks, including Stands, LangGraph, and CrewAI. The runtime also provides scaling availability and compute that many enterprises require to run production-grade agents.

    We use Amazon Bedrock AgentCore Gateway to connect to all three MCP servers. When deploying agents at scale, gateways are indispensable components to reduce management tasks like custom code development, infrastructure provisioning, comprehensive ingress and egress security, and unified access. These are essential enterprise functions needed when bringing a workload to production. In this application, we create gateways that connect all three MCP servers as targets using server-sent events. Gateways work alongside Amazon Bedrock AgentCore Identities to provide secure credentials management and secure identity propagation from the user to the communicating entities. The sample application uses AWS Identity and Access Management (IAM) for identity management and propagation.

    Incident investigation is often a multi-step process. It involves iterative hypothesis testing, multiple rounds of querying, and building context over time. We use Amazon Bedrock AgentCore Memory for this purpose. In this solution, we use session-based namespaces to maintain separate conversation threads for different investigations. For example, when a user asks “What about Payment service?” during an investigation, the agent retrieves recent conversation history from memory to maintain awareness of prior findings. We store both user questions and agent responses with timestamps to help the agent reconstruct the conversation chronologically and reason about already completed findings.

    We configured the observability agent to use Anthropic’s Claude Sonnet v4.5 in Amazon Bedrock for reasoning. The model interprets questions, decides which MCP tool to invoke, analyzes the results, and formulates the set of questions or conclusions. We use a system prompt to instruct the model to think like an experienced SRE or an operation center engineer: “Starting with a high-level check, narrowing down affected components, correlate across telemetry signal types and derive conclusion with substantiation. You ask the model to also suggest logical next steps such as performing a drill down to investigate inter service dependencies.” This makes the agent versatile to analyze and reason about common varieties of incident investigations.

    Observability agent in action

    We built a real-time RED (rate, errors, duration) metrics dashboards for the entire application, as shown in the following figure.

    To establish a baseline, we asked the agent the following question: “Are there any errors in my application in the last five minutes?”The agent queries the traces and metrics, analyzes the results, and responds saying there are no errors in the system. It notes that all the services are active, traces are healthy, and the system is processing requests normally. The agent also proactively suggests next steps that might be useful for further investigation.

    Introducing failures

    The OpenTelemetry demo application has a feature flag that we can use to introduce deliberate failures in the system. It also includes load generation so these errors can surface prominently. We use these features to introduce a few failures with the payment service. The real-time RED metrics dashboards in the previous figure reflect the impact and show the error rates climbing.

    Investigation and root cause analysis

    Now that we are generating errors, we engage the agent again. This is typically the start of the investigation session. Also, we have workflows like alarms triggering or pages going out that will trigger the starting of an investigation.

    We ask the question “Users are complaining that it is taking a long time to buy items. Can you check to see what is going on?”

    The agent retrieves the conversation history from memory (if there is any), invokes tools to query RED metrics across services, and analyzes the results. It identifies a critical purchase flow performance issue: payment service is in a connectivity crisis and completely unavailable, with extreme latency observed in fraud detection, ad service, and recommendation service. The agent provides immediate action recommendations—restore payment service connectivity as the top priority—and suggests next steps, including investigating payment service logs.

    Following the agent’s suggestion, we ask it to investigate the logs: “Investigate payment service logs to understand the connectivity issue.”

    The agent searches logs for the checkout and payment services, correlates them with trace data, and analyzes service dependencies from the service map. It confirms that although cart service, product catalog service, and currency service are healthy, the payment service is completely unreachable, successfully identifying the root cause of our deliberately introduced failure.

    Beyond root cause: Analyzing business impact

    As mentioned earlier, we have synthetic business sales and revenue data in a separate MCP server, so when the user asks the agent “Analyze the business impact of the checkout and payment service failures,” the agent uses this business data, examines the transaction data from traces, calculates estimated revenue impact, and assesses customer abandonment rates due to checkout failures. This shows how the agent can go beyond identifying the root cause and provide help with operational activities like creating a runbook for issue resolution in the future, which can be first the step to providing automatic remediation without involving SREs.

    Benefits and results

    Although the failure scenario in this post is simplified for illustration, it highlights several key benefits that directly contribute to reducing MTTR.

    Accelerated investigation cycles

    Traditional workflows for troubleshooting involve multiple iterations of hypotheses, verification, querying, and data analysis at each step, requiring context switching and consuming hours of effort. The observability agent reduces these drastically to a few minutes by autonomous reasoning, correlation, and actioning, which in turn reduces MTTR.

    Handling complex workflows

    Real-world production scenarios often involve cascading failures and multiple system failures. The observability agent’s capabilities can extend to these scenarios by using historical data and pattern recognition. For instance, it can distinguish related issues from false positives using temporal or identity-based correlation, dependency graphs, and other techniques, helping SREs avoid wasted investigation effort on unrelated anomalies.

    Rather than provide a single answer, the agent can provide probabilistic distribution across potential root causes, helping SREs prioritize remediation methods; for example:

    • Payment service network connectivity issue: 75%
    • Downstream payment gateway timeout: 15%
    • Database connection pool exhaustion: 8%
    • Other/Unknown: 2%

    The agent can compare current symptoms against past incidents, identifying whether similar patterns have happened in the past, thereby evolving from a reactive query tool into a proactive diagnostic assistant.

    Conclusion

    Incident investigation remains largely manual. SREs juggle dashboards, craft queries, and correlate signals under pressure, even when all the data is readily available. In this post, we showed how an observability agent built with Amazon Bedrock AgentCore and OpenSearch Service can alleviate this cognitive burden by autonomously querying logs, traces, and metrics; correlating findings; and guiding SREs toward root cause faster. Although this pattern represents one approach, the flexibility of Amazon Bedrock AgentCore combined with the search and analytics capabilities of OpenSearch Service enables agents to be designed and deployed in numerous ways—at different stages of the incident lifecycle, with varying levels of autonomy, or focused on specific investigation tasks—to suit your organization’s unique operational needs. Agentic AI doesn’t replace existing observability investment, but amplifies them by providing an effective way to use your data during incident investigations.


    About the authors

    Muthu Pitchaimani

    Muthu Pitchaimani

    Muthu is a Search Specialist with Amazon OpenSearch Service. He builds large-scale search applications and solutions. Muthu is interested in the topics of networking and security, and is based out of Austin, Texas.

    Jon Handler

    Jon Handler

    Jon is Director of Solutions Architecture for Search Services at AWS. Based in Palo Alto, CA. Jon works closely with OpenSearch and Amazon OpenSearch Service, providing help and guidance to a broad range of customers who have generative AI, search, and log analytics workloads for OpenSearch.

    Mastering millisecond latency and millions of events: The event-driven architecture behind the Amazon Key Suite

    Post Syndicated from Ali Ufuk Yucel original https://aws.amazon.com/blogs/architecture/mastering-millisecond-latency-and-millions-of-events-the-event-driven-architecture-behind-the-amazon-key-suite/

    Background

    Amazon Key empowers customers to securely manage access to their homes and businesses through innovative solutions. Through a suite of consumer and business products, the Amazon Key team is transforming how customers receive deliveries and manage access to their spaces. Our In-Garage Delivery service offers a secure and convenient solution for receiving Amazon packages and groceries directly inside customers’ garages. For property managers and building owners, Amazon Key provides comprehensive access management solutions that enable safe and efficient delivery operations in apartment buildings and gated communities, enhancing both security and convenience for residents.

    In this post, we explore how the Amazon Key team used Amazon EventBridge to modernize their architecture, transforming a tightly coupled monolithic system into a resilient, event-driven solution. We explore the technical challenges we faced, our implementation approach, and the architectural patterns that helped us achieve improved reliability and scalability. The post covers our solutions for managing event schemas at scale, handling multiple service integrations efficiently, and building an extensible architecture that accommodates future growth.

    Opportunities

    Service Coupling and System Fragility

    Our legacy architecture faced significant challenges stemming from its tightly coupled design, where service interactions created a complex web of dependencies impacting system stability and scalability. Making service modifications was particularly challenging, as adding or removing services required careful consideration of numerous interdependencies. An incident highlighted this vulnerability when an issue in Service-A triggered a cascade of failures across many upstream services, with increased timeouts leading to retry attempts and ultimately resulting in service deadlocks. System fragility was further demonstrated when problems with a single device vendor, despite being responsible only for specific delivery operations, caused widespread degradation across multiple system services.

    Loose Event Schemas

    Our old event management infrastructure lacked explicit schema definitions and employed a loosely-typed data architecture, leading to several critical issues. Events were difficult to maintain as use cases expanded, and the absence of formal schema documentation impacted transparency and team collaboration. The design made it almost impossible to implement backward-incompatible changes, such as removing unused fields or events for performance optimization. Without a repository for schema management, team-to-team collaboration for schema modifications (adding fields, removing fields, deprecating fields, or marking fields as required) became challenging. The system also lacked organized validation logic, making it difficult for publishers to identify invalid events before they entered the system. Additionally, the loosely typed schemas lost important semantic context, such as inheritance and composition relationships between different event schemas.

    Inconsistent Event Routing and Management

    The event routing logic was manually managed and lacked the sophistication needed for growing use cases. The system only supported basic validation of events, primarily checking for required fields, with limited capability for extending validation rules or implementing more complex routing logic. Features that were commonly available in off-the-shelf solutions, such as parallel publishing to multiple subscribers, required significant custom development and ongoing maintenance effort. The implementation only supported a limited number of subscribers to the event pipeline, with no sustainable pathway for adding more consumers. While attempts were made to reduce coupling through SNS/SQS pairs between services, these solutions were implemented on an ad-hoc basis, lacking standardization and creating additional maintenance overhead. This approach led to redundant work and failed to abstract away common functionality, resulting in an inefficient and hard-to-maintain system.These challenges collectively highlighted the need for a more robust and flexible architectural approach that could better serve the system’s evolving needs while improving reliability, maintainability, and scalability.

    Design

    Given our requirements and the architectural challenges we faced, we implemented a single-bus, multi-account pattern to optimize our system architecture. In this design, each service team maintains complete ownership and autonomy over their application stack, enabling independent development and deployment cycles. Meanwhile, our DevOps team manages a centralized infrastructure stack that encompasses event bus rules, target configurations, and service integrations. This separation of concerns provides several key benefits:

    1. Clear ownership boundaries: Service teams can focus on their core business logic while leveraging a standardized event infrastructure.
    2. Centralized governance: The DevOps team facilitates consistent event routing patterns, security controls, and monitoring across service integrations.
    3. Simplified operations: A single event bus reduces operational complexity while maintaining logical separation through well-defined routing rules.
    4. Enhanced security: The multi-account structure provides natural isolation boundaries while still enabling controlled cross-account event flows.
    5. Streamlined compliance: Centralized management of data exchange patterns makes it easier to implement and maintain compliance requirements.

    While EventBridge provided the foundation, we developed additional components to meet our specific requirements.  Our team built three key components: a schema repository serving as the single source of truth for event definitions, a client library that handles schema validation and provides developer-friendly abstractions, and an infrastructure library offering reusable components for subscriber integration.

    Event Schema Repository

    Amazon EventBridge’s schema discovery and documentation capabilities provide powerful solutions for managing event-driven architectures. The service automatically captures event structures in the schema registry, maintaining versions as events evolve over time. While EventBridge provides developers with tools to implement validation using external solutions or custom application code, it currently does not include native schema validation capabilities. For our organization’s large-scale event-driven architecture, schema validation was a critical requirement. We evaluated two implementation approaches: a centralized validation service or client-side validation at the publisher/subscriber level. The centralized approach would have required managing additional infrastructure, scaling considerations, and introduced latency through extra network hops. After analyzing these factors alongside our requirements for schema governance and team autonomy, we implemented a custom schema repository with client-side validation.

    This architecture prioritizes developer experience through immediate validation feedback while maintaining our standards for schema versioning and release management. The repository serves as the foundation for our event-driven architecture, providing essential capabilities for data governance and quality control. By acting as the single source of truth for event definitions, it enables standardized validation across clients, enforces data quality checks, establishes clear ownership boundaries, and maintains comprehensive audit trails for schema changes. Publishers and subscribers leverage these schemas to maintain data consistency and compatibility as their services evolve. The repository has become instrumental in facilitating efficient cross-team collaboration through self-service schema discovery, documentation, and automated validation during development. It maintains a comprehensive registry of event publishers and their corresponding subscribers, providing clear visibility into event flow patterns and dependencies across the system. Teams can quickly manage schema evolution with clear deprecation policies and migration paths, while the system helps detect breaking changes early in the development cycle. This collaborative approach has significantly improved team velocity and reduced integration issues between services.

    {
        "$schema": "http://json-schema.org/draft-04/schema#",
        "$id": "/resource/event/schema/EventV1.json",
        "title": "EventV1",
        "description": "Schema for a simple event.",
        "type": "object",
        "properties": {
            "id": {
                "description": "Id of the event.",
                "type": "string"
            },
            "type": {
                "description": "Type of the event.",
                "$ref": "EventType.json"
            },
            "time": {
                "description": "Time at which the event occurred. It uses ISO 8601 Date Time Format. Reference: https://www.iso.org/iso-8601-date-and-time-format.html",
                "type": "string",
                "format": "date-time"
            },
            "publisher": {
                "description": "Publisher of the event.",
                "$ref": "../core/Publisher.json"
            }
        },
        "required": [
            "id",
            "type",
            "time",
            "publisher"
        ]
    }

    Client Library

    The client library serves as a crucial component for both publishers and subscribers, streamlining their integration with the central event bus. At its core, the library leverages our Event Schema Repository, generating code bindings at build time to provide developers with type-safe and intuitive interfaces for event creation and handling. This approach significantly enhances developer productivity by offering straightforward and convenient methods to construct events and interact with the bus, reducing the likelihood of errors and improving code readability.

    A key feature of the client library is its built-in validation mechanism. By utilizing the schemas from our local repository, the library performs thorough validation of events before they are published. This proactive approach catches potential issues early in the development cycle, making sure that only well-formed events conforming to the agreed-upon schemas make it to the event bus. Once validated, the library handles the serialization process and manages the actual publishing of events to the bus, abstracting and simplifying data transformation and transport.

    For subscribers, the client library offers equally valuable functionality. It seamlessly handles the deserialization of incoming events, presenting them to the subscribing services in a readily usable format. This feature saves development time and reduces the risk of parsing errors, allowing teams to focus on business logic rather than data handling intricacies. By providing these comprehensive capabilities, our client library has become an indispensable tool in our event-driven network, promoting consistency, reliability, and efficiency across our microservices architecture.

    Subscriber Constructs Library

    We developed a subscriber constructs library using AWS Cloud Development Kit (CDK) to simplify and standardize the integration process with our central event bus. This library abstracts the setup and management of underlying infrastructure required for event consumption, enabling teams to focus on their core business logic rather than infrastructure configuration details.

    The library automates the creation of essential components required for reliable event processing. It provisions a dedicated event bus within the subscriber’s account, establishes the necessary IAM roles and permissions for secure cross-account communication with the central event bus, and configures standardized monitoring and alerting for event processing. This automation not only reduces the potential for configuration errors but also facilitates consistent implementation of our architectural patterns across different teams.

    /**
     * Subscriber implementation to provision necessary AWS infrastructure.
     *
     */
    const subscription = new Subscription(scope, id, {
        name: "DeliveryService", // Name of your application
        application: {
           region: Region.US_EAST_1, // Region of your Application
        },
    });
    

    Conclusion

    Amazon Key team’s journey to modernize their architecture and build a resilient, event-driven solution exemplifies the powerful benefits of leveraging AWS EventBridge and adopting a well-designed event-driven architecture. By addressing the challenges of service coupling, loose event schemas, and inconsistent event routing, the team was able to transform their system into a more reliable, scalable, and maintainable resource. The key architectural patterns and components they implemented have had a significant impact on their ability to deliver innovative solutions to their customers.

    Reliability and Scale:

    • Built a decoupled event system processing 2000 events/second with 99.99% success rate
    • Achieved consistent 80ms p90 latency from ingestion to target invocation across 14M subscriber calls
    • Avoided the need for new infrastructure for event exchange through standardized event routing
    • Enabled migration of existing complex interdependencies to event-driven architecture

    Developer Experience:

    • Reduced service integration time for new use cases from five days to one day (80% improvement)
    • New event onboarding on the Custom Event Schema repository now takes four hours, down from 48 hours
    • Publisher/subscriber integration completed in eight hours, previously took 40 hours
    • Standardized client library addressed 90% of common integration errors

    Security and Governance :

    • Single control plane manages 100% of event bus infrastructure
    • Automated security compliance checks catch 100% of unauthorized data exchange patterns
    • Real-time monitoring dashboard tracks every event flow and schema change
    • Schema repository provides complete audit trail for system modifications

    The solutions developed by the Amazon Key team provide a blueprint for other organizations looking to modernize their architectures and leverage the power of event-driven design patterns. By adopting similar architectural patterns and components, such as the schema repository and client libraries, other organizations can be empowered to achieve similar benefits.


    About the authors

    Build an AI-powered course recommender using Amazon Bedrock and AWS End User Messaging

    Post Syndicated from Ruchikka Chaudhary original https://aws.amazon.com/blogs/messaging-and-targeting/build-an-ai-powered-course-recommender-using-amazon-bedrock-and-aws-end-user-messaging/

    Educational technology (EdTech) providers face the challenge of maintaining seamless, personalized communication and presenting the right recommendations to their diverse stakeholders. This post explores how combining Amazon Web Services (AWS) End User Messaging and WhatsApp Business API with the advanced AI capabilities of Amazon Bedrock can transform educational engagement.

    In this post, we explore use cases that are reshaping the EdTech industry. We discover how application automation can streamline admissions and enrollment processes, making them more efficient and user-friendly. We demonstrate how instant student engagement can be achieved through AI-powered, personalized interactions that keep learners motivated and connected. We showcase how real-time course feedback mechanisms can help educators adapt and improve their teaching methods. We also examine how student support can be automated using intelligent assistants that provide continuous, all-day assistance while maintaining a personal touch.

    We show you how to build an AI-powered course recommendation system. We explain how to set up WhatsApp Business API integration with Amazon Bedrock, implement smart search capabilities for course matching, and create a scalable serverless architecture. You’ll learn how to build meaningful analytics dashboards to track engagement and learn best practices for handling errors and maintaining system reliability. Whether you’re an EdTech professional or a cloud architect, this guide gives you practical insights into combining conversational AI with educational services.

    Use cases

    • An AI-powered personalized learning pathway generator that automatically recommends customized content based on individual student performance metrics and learning requirements
    • Course improvement suggestions and real-time course feedback
    • A smart communication orchestrator that delivers role-specific, automated notifications and updates across multiple channels to enhance student and parent engagement
    • An early warning system using predictive analytics to identify at-risk students through real-time monitoring of engagement metrics and performance indicators
    • Student support automation with always available AI assistant support, FAQ handling, escalation management, and multilingual support

    Prerequisites

    • An AWS account
    • AWS End User Messaging set up with WhatsApp channel enabled
    • A pre-existing WhatsApp Business account
    • Amazon Bedrock setup must be completed with preferred model
    • Amazon Quick Sight for the AWS Region must be enabled

    Solution overview

    With this solution, users can discover and order educational courses through WhatsApp conversations. Instead of navigating complex websites, the user can send a WhatsApp message saying, “I want to learn Python programming.” They’ll receive personalized course recommendations instantly. The architecture processes WhatsApp messages through AWS End User Messaging, uses Amazon Bedrock for AI-powered conversations, performs semantic search with Amazon OpenSearch Serverless, and captures analytics for business insights. (For step-by-step implementation and rollback guidelines, see the sample course recommendation system.) The following architectural diagram illustrates a modern AI-powered course recommendation system that uses multiple AWS services.

    Figure 1: AI-powered course recommendation system

    Message processing

    When users send WhatsApp messages, AWS End User Messaging captures them and publishes events to an Amazon Simple Notification Service (Amazon SNS) topic. This creates a decoupled architecture where multiple services can process the same message events independently. AWS Lambda functions subscribe to these events, facilitating reliable message processing during high-traffic periods. The decoupled design provides several advantages:

    • If one component fails, others continue operating
    • You can add new message processors without affecting existing ones
    • The system automatically scales based on message volume without manual intervention

    AI conversation engine

    Amazon Bedrock with Claude 3 Haiku powers natural language understanding. It is configured specifically for WhatsApp with instructions for short paragraphs, relevant emoji, and mobile-optimized responses.

    AI agents

    The agent maintains conversation context and handles structured actions such as course search, detail retrieval, and booking through defined functions. The following workflow is the agent action flow and sample code:

    Agent flow

    1. Greets user → Understands intent → Searches courses → Provides details → Facilitates booking
    2. Maintains context throughout the conversation
    3. Can switch between actions based on user responses
    4. Handles complex queries by combining multiple actions

    Sample code

    The following is sample code to create a Bedrock agent using AWS CDK:

        agent = bedrock.CfnAgent(foundation_model="anthropic.claude-3-haiku-20240307-v1:0",
         instruction="""
         Format for WhatsApp: short paragraphs,
            focus on technical courses only
           """,
          action_groups=[# Functions for search, details, booking]
    )

    Semantic search

    Traditional keyword search can miss the user’s intent. The application uses Amazon Titan Embeddings in Amazon Bedrock to convert courses and queries into vectors, enabling semantic understanding. When users ask for “cloud computing courses,” the system can understand related terms such as “AWS” and “serverless” without exact matches. Amazon OpenSearch Serverless handles vector similarity matching combined with traditional filters for course price, level, and duration.

    Analytics pipeline

    Every WhatsApp message interaction generates business intelligence. Messages are stored in Amazon Simple Storage Service (Amazon S3) with date partitioning, catalogued through AWS Glue, and made queryable using Amazon Athena. Teams can analyze user behavior, popular topics, and conversion rates through Quick Sight dashboards. The following dashboard shows example widgets displaying pie-chart breakdown of message delivery status and count of messages per day.

    Figure 2: Amazon Quick Sight dashboard

    As shown in the following dashboard, Amazon Q in QuickSight enables you to explore and analyze your data using conversational AI capabilities.

    Figure 3: Amazon Quick Sight dashboard showing chat window

    Error handling and resilience

    Such highly scalable and distributed solutions require robust error handling. The application has exponential backoff and retries for API calls, meaning the system can gracefully handle rate limits and temporary service unavailability.

    The following is sample code for error handling and resilience:

    python
    def retry_with_backoff(func, max_retries=5):
    retries = 0
    backoff = 1
    while retries < max_retries:
    try:
    return func()
    except ThrottlingException:
    sleep_time = backoff + random.uniform(0, 1)
    time.sleep(sleep_time)
    backoff = min(backoff * 2, 32)
    retries += 1
    raise Exception("Max retries exceeded")

    Business impact

    With the global EdTech market expected to reach $165 billion by 2026, educators and institutions are seeking solutions to prevent student dropouts, improve learning outcomes, and maintain their competitive advantage. Poor personalization can lead to decreased student engagement, lower course completion rates, and ultimately revenue loss.

    Implementing AI-driven personalization and communication systems means institutions can significantly improve student retention rates, boost learning outcomes, and create a more engaging educational experience, which directly impacts their bottom line and reputation in an increasingly competitive educational landscape. This solution could transform educational delivery through intelligent personalization and operational excellence. A serverless architecture can help educational institutions focus on content quality rather than infrastructure management while potentially maintaining rapid response times for course searches. The system’s analytics capabilities could offer insights into student behavior and course preferences, helping shape future curriculum development.

    With mobile optimization, institutions can better serve the growing population of digital-first learners. The combination of automated scaling and pay-per-use pricing could create opportunities for cost optimization, and real-time dashboards can be used to facilitate data-informed decision-making. Such improvements in user experience and operational efficiency could lead to enhanced student engagement and institutional growth in the evolving education environment.

    Sample conversation

    The following video shows how a user can interact with the generative AI-powered course recommendation system and receive course recommendations.

    Future enhancements

    We’re expanding to more messaging platforms, adding voice integration through Amazon Connect, and implementing predictive analytics for personalized recommendations. The serverless architecture makes these additions straightforward without infrastructure changes. Future scenarios could involve:

    • Educator and student support – This solution can be enhanced for student and educator experiences. For educators, it can automate administrative tasks. For students, it can create personalized engagement campaigns, a communication approach that could be significantly more effective than traditional methods.
    • Digital admission process flow – The solution integrates AWS Bedrock AI with WhatsApp Business API to streamline digital admissions. It can enable instant document verification, guide secure payments, and provide automated updates, all within the AWS End User Messaging WhatsApp channel. This AI-powered system could transform the complex admission process into an efficient, chat-based experience, benefiting both institutions and applicants.
    • Parental support and study material management – The system could intelligently distribute learning resources based on student needs, send automated schedule updates, and provide personalized progress reports to parents through WhatsApp. Parents could receive AI-curated study materials and real-time updates about their child’s academic performance, homework assignments, and upcoming assessments through familiar chat interactions. This integration could transform traditional parent-teacher communication into an efficient, automated system while providing timely access to relevant educational resources.

    Conclusion

    The WhatsApp course recommender agent demonstrates how modern AWS services can create sophisticated, AI-powered conversational experiences that scale automatically and provide rich business insights. The serverless architecture provides cost-effectiveness while maintaining enterprise-grade reliability. Key architectural principles that make this solution successful include event-driven design for scalability, AI integration for natural interactions, semantic search for superior user experience, customizable analytics for business intelligence, and infrastructure as code (IaC) for reliable deployments.

    For organizations considering similar implementations, we recommend focusing on user experience optimization, robust error handling, comprehensive monitoring, and gradual feature rollout. The conversational AI environment is rapidly evolving, and solutions that prioritize user experience while maintaining technical excellence can drive the most business value. This implementation can serve as a reference architecture for building production-ready conversational AI systems on AWS, demonstrating patterns that can apply across industries and use cases.


    About the authors

    Use Amazon MSK Connect and Iceberg Kafka Connect to build a real-time data lake

    Post Syndicated from Xiao Huang original https://aws.amazon.com/blogs/big-data/use-amazon-msk-connect-and-iceberg-kafka-connect-to-build-a-real-time-data-lake/

    As analytical workloads increasingly demand real-time insights, organizations need business data to enter the data lake immediately after generation. While various methods exist for real-time CDC data ingestion (such as AWS Glue and Amazon EMR Serverless), Amazon MSK Connect with Iceberg Kafka Connect provides a fully managed, streamlined approach that reduces operational complexity and enables continuous data synchronization.

    In this post, we demonstrate how to use Iceberg Kafka Connect with Amazon Managed Streaming for Apache Kafka (Amazon MSK) Connect to accelerate real-time data ingestion into data lakes, simplifying the synchronization process from transactional databases to Apache Iceberg tables.

    Solution overview

    In this post, we show you how to implement capturing transaction log data from Amazon Relational Database Service (Amazon RDS) for MySQL and writing it to Amazon Simple Storage Service (Amazon S3) in Iceberg table format using append mode, covering both single-table and multi-table synchronization, as shown in the following figure.

    Downstream consumers then process these change records to reconstruct the data state before writing to Iceberg tables.

    In this solution, you use the Iceberg Kafka Sink Connector to implement the business on the sink side. The Iceberg Kafka Sink Connector has the following features:

    • Supports exactly-once delivery
    • Support multi-table synchronization
    • Support schema changes
    • Field name mapping through Iceberg’s column mapping feature

    Prerequisites

    Before beginning the deployment, ensure you have the following components in place:

    Amazon RDS for MySQL: This solution assumes you already have an Amazon RDS for MySQL database instance running with the data you want to synchronize to your Iceberg data lake. Ensure that binary logging is enabled on your RDS instance to support Change Data Capture (CDC) operations.

    Amazon MSK Cluster: You need an Amazon MSK cluster provisioned in your target AWS Region. This cluster will serve as the streaming platform between your MySQL database and the Iceberg data lake. Ensure the cluster is properly configured with appropriate security groups and network access.

    Amazon S3 Bucket: Ensure you have an Amazon S3 bucket ready to host the custom Kafka Connect plugins. This bucket serves as the storage location from which AWS MSK Connect retrieves and installs your plugins. The bucket must exist in your target AWS Region, and you must have appropriate permissions to upload objects to it.

    Custom Kafka Connect Plugins: To enable real-time data synchronization with MSK Connect, you need to create two custom plugins. The first plugin uses the Debezium MySQL Connector to read transactional logs and produce Change Data Capture (CDC) events. The second plugin uses Iceberg Kafka Connect to synchronize data from Amazon MSK to Apache Iceberg tables.

    Build Environment: To build the Iceberg Kafka Connect plugin, you need a build environment with Java and Gradle installed. You can either launch an Amazon EC2 instance (recommended: Amazon Linux 2023 or Ubuntu) or use your local machine if it meets the requirements. Ensure you have sufficient disk space (at least 20GB) and network connectivity to clone the repository and download dependencies.

    Build Iceberg Kafka Connect from open source

    The connector ZIP archive is created as part of the Iceberg build. You can run the build using the following code:

    git clone https://github.com/apache/iceberg.git
    cd iceberg/
    ./gradlew -x test -x integrationTest clean build
    The ZIP archive will be saved in ./kafka-connect/kafka-connect-runtime/build/distributions.

    Create custom plugins

    The next step is to create custom plugins to read and synchronize the data.

    1. Upload the custom plugin ZIP file you compiled in the previous step to your designated Amazon S3 bucket.
    2. Go to the AWS Management Console and navigate to Amazon MSK and choose Connect in the navigation pane.
    3. Choose Custom plugins, then select the plugin file you uploaded to S3 by browsing or entering its S3 URI.
    4. Specify a unique, descriptive name for your custom plugin (such as my-connector-v1).
    5. Choose Create custom plugin.

    Configure MSK Connect

    With the plugins installed, you’re ready to configure MSK Connect.

    Configure data source access

    Start by configuring data source access.

    1. To create a worker configuration, choose Worker configurations in the MSK Connect console.
    2. Choose Create worker configuration and copy and paste the following configuration.
      key.converter.schemas.enable=false
      value.converter.schemas.enable=false
      key.converter=org.apache.kafka.connect.json.JsonConverter
      value.converter=org.apache.kafka.connect.json.JsonConverter
      # Enable topic creation by the worker
      topic.creation.enable=true
      # Default topic creation settings for debezium connector
      topic.creation.default.replication.factor=3
      topic.creation.default.partitions=1
      topic.creation.default.cleanup.policy=delete

    3. In the Amazon MSK console, choose Connectors under Amazon MSK Connect and choose Create connector.
    4. In the setup wizard, select the Debezium MySQL Connector plugin created in the previous step, enter the connector name and select the MSK cluster of the synchronization target. Copy and paste the following content in the configuration:
      
      connector.class=io.debezium.connector.mysql.MySqlConnector
      tasks.max=1
      include.schema.changes=false
      database.server.id=100000
      database.server.name=
      database.port=3306
      database.hostname=
      database.password=
      database.user=
      
      topic.creation.default.partitions=1
      topic.creation.default.replication.factor=3
      
      topic.prefix=mysqlserver
      database.include.list=
      
      ## route
      transforms=Reroute
      transforms.Reroute.type=io.debezium.transforms.ByLogicalTableRouter
      transforms.Reroute.topic.regex=(.*)(.*)
      transforms.Reroute.topic.replacement=$1all_records
      
      # schema.history
      schema.history.internal.kafka.topic
      schema.history.internal.kafka.bootstrap.servers=
      # IAM/SASL
      schema.history.internal.consumer.sasl.mechanism=AWS_MSK_IAM
      schema.history.internal.consumer.sasl.client.callback.handler.class=software.amazon.msk.auth.iam.IAMClientCallbackHandler
      schema.history.internal.consumer.security.protocol=SASL_SSL
      schema.history.internal.consumer.sasl.jaas.config=software.amazon.msk.auth.iam.IAMLoginModule required;
      schema.history.internal.producer.security.protocol=SASL_SSL
      schema.history.internal.producer.sasl.mechanism=AWS_MSK_IAM
      schema.history.internal.producer.sasl.client.callback.handler.class=software.amazon.msk.auth.iam.IAMClientCallbackHandler
      schema.history.internal.producer.sasl.jaas.config=software.amazon.msk.auth.iam.IAMLoginModule required;

      Note that in the configuration, Route is used to write multiple records to the same topic. In the parameter transforms.Reroute.topic.regex, the regular expression is configured to filter the table names that need to be written to the same topic. In the following example, the data containing <tablename-prefix> in the table name is written to the same topic.

      ## route
      transforms=Reroute
      transforms.Reroute.type=io.debezium.transforms.ByLogicalTableRouter
      transforms.Reroute.topic.regex=(.*)(.*)
      transforms.Reroute.topic.replacement=$1all_records

      For example, after transforms.Reroute.topic.replacement is specified as $1all_records, the topic name created in the MSK is < database.server.name>.all_records.

    5. After you choose Create, MSK Connect creates a synchronization task for you.

    Data synchronization (single table mode)

    Now, you can create a real-time synchronization task for the Iceberg table. Start by creating a real-time synchronization job for a single table.

    1. In the Amazon MSK console, choose Connectors under MSK Connect
    2. Choose Create connector.
    3. On the next page, select the previously created Iceberg Kafka Connect plugin
    4. Enter the connector name and select the MSK cluster of the synchronization target.
    5. Paste the following code in the configuration.
      
      connector.class=org.apache.iceberg.connect.IcebergSinkConnector
      tasks.max=1
      topics=
      iceberg.tables=
      iceberg.catalog.catalog-impl=org.apache.iceberg.aws.glue.GlueCatalog
      iceberg.catalog.warehouse=
      iceberg.catalog.io-impl=org.apache.iceberg.aws.s3.S3FileIO
      iceberg.catalog.client.region=
      iceberg.tables.auto-create-enabled=true
      iceberg.tables.evolve-schema-enabled=true
      iceberg.control.commit.interval-ms=120000
      transforms=debezium
      transforms.debezium.type=org.apache.iceberg.connect.transforms.DebeziumTransform
      key.converter=org.apache.kafka.connect.json.JsonConverter
      value.converter=org.apache.kafka.connect.json.JsonConverter
      value.converter.schemas.enable=false
      key.converter.schemas.enable=false
      iceberg.control.topic=control-iceberg

      For Iceberg Connector, it will create a topic named control-iceberg by default to record offset. Select the previously created worker configuration that includes topic.creation.enable = true. If you use the default worker configuration and auto-topic creation isn’t enabled at the MSK broker level, the connector will not be able to automatically create topics.

      You can also specify this topic name by setting the parameter iceberg.control.topic = <offset-topic>. If you want to use a custom topic, you can use the following code.

      $KAFKA_HOME/bin/kafka-topics.sh --bootstrap-server $MYBROKERS --create --topic <my-iceberg-offset-topic> --partitions 3 --replication-factor 2 --config cleanup.policy=compact

    6. Query the synchronized data results through Amazon Athena. From the table synchronized to Athena, you can see that, in addition to the source table field, an additional _cdc field has been added to store the metadata content of the CDC.

    Compaction

    Compaction is an essential maintenance operation for Iceberg tables. Although frequent ingestion of small files can negatively impact query performance, regular compaction mitigates this issue by consolidating small files, minimizing metadata overhead, and substantially improving query efficiency. To maintain optimal table performance, you should implement dedicated compaction workflows. AWS Glue offers an excellent solution for this purpose, providing automated compaction capabilities that intelligently merge small files and restructure table layouts for enhanced query performance.

    Schema Evolution Demonstration

    To demonstrate the schema evolution capabilities of this solution, we conducted a test to show how field changes at the source database are automatically synchronized to the Iceberg tables through MSK Connect and Iceberg Kafka Connect.

    Initial Setup:

    First, we created an RDS MySQL database with a customer information table (tb_customer_info) containing the following schema:

    +----------------+--------------+------+-----+-------------------+-----------------------------------------------+
    | Field          | Type         | Null | Key | Default           | Extra                                         |
    +----------------+--------------+------+-----+-------------------+-----------------------------------------------+
    | id             | int unsigned | NO   | PRI | NULL              | auto_increment                                |
    | user_name      | varchar(64)  | YES  |     | NULL              |                                               |
    | country        | varchar(64)  | YES  |     | NULL              |                                               |
    | province       | mediumtext   | NO   |     | NULL              |                                               |
    | city           | int          | NO   |     | NULL              |                                               |
    | street_address | varchar(20)  | NO   |     | NULL              |                                               |
    | street_name    | varchar(20)  | NO   |     | NULL              |                                               |
    | created_at     | timestamp    | NO   |     | CURRENT_TIMESTAMP | DEFAULT_GENERATED                             |
    | updated_at     | timestamp    | YES  |     | CURRENT_TIMESTAMP | DEFAULT_GENERATED on update CURRENT_TIMESTAMP |
    +----------------+--------------+------+-----+-------------------+-----------------------------------------------+

    We then configured MSK Connect using the Debezium MySQL Connector to capture changes from this table and stream them to Amazon MSK in real time. Following that, we set up Iceberg Kafka Connect to consume the data from MSK and write it to Iceberg tables.

    Schema Modification Test:

    To test the schema evolution capability, we added a new field named phone to the source table:

    ALTER TABLE tb_customer_info ADD COLUMN phone VARCHAR(20) NULL;

    We then inserted a new record with the phone field populated:

    INSERT INTO tb_customer_info (user_name,country,province,city,street_address,street_name,phone) values ('user_demo','China','Guangdong',755,'Street1 No.369','Street1','13099990001');

    Results:

    When we queried the Iceberg table in Amazon Athena, we observed that the phone field had been automatically added as the last column, and the new record was successfully synchronized with all field values intact. This demonstrates that Iceberg Kafka Connect’s self-adaptive schema capability seamlessly handles DDL changes at the source, eliminating the need for manual schema updates in the data lake.

    Data synchronization (multi-table mode)

    It’s common that data admins want to use a single connector for moving data in multiple tables. For example, you can use the CDC collection tool to write data from multiple tables to a topic and then write data from one topic to multiple Iceberg tables through the consumer side. In Configure data source access, you configured a MySQL synchronization Connector to synchronize tables with specified rules to a topic using Route. Now let’s review how to distribute data from this topic to multiple Iceberg tables.

    1. When using Iceberg Kafka Connect to synchronize multiple tables to Iceberg tables using AWS Glue Data Catalog, you must pre-create a database in the Data Catalog before starting the synchronization process. The database name in AWS Glue must exactly match the source database name, because the Iceberg Kafka Connect connector automatically uses the source database name as the target database name during multi-table synchronization. This naming consistency is required because the connector doesn’t provide an option to map source database names to different target database names in multi-table scenarios.
    2. If you want to use your custom topic name, you can create a new topic to store the MSK Connect record offset, see Data synchronization (single table mode).
    3. In the Amazon MSK console, create another connector using the following configuration.
      connector.class= org.apache.iceberg.connect.IcebergSinkConnector
      tasks.max=2
      topics=
      iceberg.catalog.catalog-impl=org.apache.iceberg.aws.glue.GlueCatalog
      iceberg.catalog.warehouse=
      iceberg.catalog.io-impl=org.apache.iceberg.aws.s3.S3FileIO
      iceberg.catalog.client.region=
      iceberg.tables.auto-create-enabled=true
      iceberg.tables.evolve-schema-enabled=true
      iceberg.control.commit.interval-ms=120000
      transforms=debezium
      transforms.debezium.type=org.apache.iceberg.connect.transforms.DebeziumTransform
      iceberg.tables.route-field=_cdc.source
      iceberg.tables.dynamic-enabled=true
      key.converter=org.apache.kafka.connect.json.JsonConverter
      value.converter=org.apache.kafka.connect.json.JsonConverter
      value.converter.schemas.enable=false
      key.converter.schemas.enable=false
      iceberg.control.topic=control-iceberg

      In this configuration, two parameters have been added:

      • iceberg.tables.route-field: Specifies the routing field that distinguishes between different tables, specified as cdc.source for CDC data parsed by Debezium
      • iceberg.tables.dynamic-enabled: If the iceberg.tables parameter isn’t set, it must be specified as true here
    4. After completion, MSK Connect will creates a sink connector for you.
    5. After the process is complete, you can view the newly created table through Athena.

    Other tips

    In this section, we share some more things that you can use to customize your deployment to fit your use case.

    • Specified table synchronizationIn the Data synchronization (multi-table mode) section, you specify iceberg.tables.route-field = _cdc.Source and iceberg.tables.dynamic-enabled=true, these two parameter settings can write multiple tables stored in the Iceberg table. If you want to synchronize only the specified tables, you can specify the table name you want to synchronize by setting iceberg.tables.dynamic-enabled = false and then setting the iceberg.tables parameter. For example,
      iceberg.tables.dynamic-enabled = false
      iceberg.tables = default.tablename1,default.tablename2
       
      iceberg.table.default.tablename1.route-regex = tablename1
      iceberg.table.default.tablename2.route-regex = tablename2

    • Performance Testing Results
      We conducted a performance test using sysbench to evaluate the data synchronization capabilities of this solution. The test simulated a high-volume write scenario to demonstrate the system’s throughput and scalability.Test Configuration:

      1. Database setup: Created 25 tables in the MySQL database using sysbench
      2. Data loading: Wrote 20 million records to each table (500 million total records)
      3. Real-time streaming: Configured MSK Connect to stream data from MySQL to Amazon MSK in real time during the write process
      4. Kafka Connect configuration:
        • Started Kafka Iceberg Connect
        • Minimum workers: 1
        • Maximum workers: 8
        • Allocated two MCUs per worker

      Performance Results:

      In our test using the configuration above, each MCU achieved peak writing performance of approximately 10,000 records per second, as shown in the following figure. This demonstrates the solution’s ability to handle high-throughput data synchronization workloads effectively.

    Clean up

    To clean up your resources, complete the following steps:

    1. Delete MSK Connect connectors: Remove both the Debezium MySQL Connector and Iceberg Kafka Connect connector created for this solution.
    2. Delete the Amazon MSK cluster: If you created a new MSK cluster specifically for this demonstration, delete it to stop incurring charges.
    3. Delete the S3 buckets: Remove the S3 buckets used to store the custom Kafka Connect plugins and Iceberg table data. Ensure you have backed up any data you need before deletion.
    4. Delete the EC2 instance: If you launched an EC2 instance to build the Iceberg Kafka Connect plugin, terminate it.
    5. Delete the RDS MySQL instance (optional): If you created a new RDS instance specifically for this demonstration, delete it. If you’re using an existing production database, skip this step.
    6. Remove IAM roles and policies (if created): Delete any IAM roles and policies that were created specifically for this solution to maintain security best practices.

    Conclusion

    In this post, we presented a solution to achieve real-time, efficient data synchronization from transactional databases to data lakes using Amazon MSK Connect and Iceberg Kafka Connect. This solution provides a low-cost and efficient data synchronization paradigm for enterprise-level big data analysis. Whether you’re working with ecommerce transactions, financial transactions, or IoT device logs, this solution can help you achieve quick access to a data lake, enabling analytical businesses to quickly obtain the latest business data. We encourage you to try this solution in your own environment and share your experiences in the comments section. For more information, visit Amazon MSK Connect.


    About the author

    Huang Xiao

    Huang Xiao

    Huang is a Senior Specialist Solution Architect with Analytics at AWS. He focuses on big data solution architecture design, with years of experience in development and architectural design within the big data field.

    Optimizing Flink’s join operations on Amazon EMR with Alluxio

    Post Syndicated from Qingyuan Tang original https://aws.amazon.com/blogs/big-data/optimizing-flinks-join-operations-on-amazon-emr-with-alluxio/

    When you’re working with data analysis, you often face the challenge of effectively correlating real-time data with historical data to gain actionable insights. This becomes particularly critical when you’re dealing with scenarios like e-commerce order processing, where your real-time decisions can significantly impact business outcomes. The complexity arises when you need to combine streaming data with static reference information to create a comprehensive analytical framework that supports both your immediate operational needs and strategic planning

    To tackle this challenge, you can employ stream processing technologies that handle continuous data flows while seamlessly integrating live data streams with static dimension tables. These solutions enable you to perform detailed analysis and aggregation of data, giving you a comprehensive view that combines the immediacy of real-time data with the depth of historical context. Apache Flink has emerged as a leading stream computing platform that offers robust capabilities for joining real-time and offline data sources through its extensive connector ecosystem and SQL API.

    In this post, we show you how to implement real-time data correlation using Apache Flink to join streaming order data with historical customer and product information, enabling you to make informed decisions based on comprehensive, up-to-date analytics.

    We also introduce an optimized solution to automatically load Hive dimension table data into Alluxio Universal Flash Storage (UFS) through the Alluxio cache layer. This enables Flink to perform temporal joins on changing data, accurately reflecting the content of a table at specific points in time.

    Solution architecture

    When it comes to joining Flink SQL tables with stream tables, the lookup join is a go-to method. This approach is particularly effective when you need to correlate streaming data with static or slowly changing data. In Flink, you can use connectors like the Flink Hive SQL connector or the FileSystem connector to archive the scenario.

    The following architecture shows general approach which we describe ahead:

    Here’s how we do this:

    1. We use offline data to construct a Flink table. This data could be from an offline Hive database table or from files stored in a system like Amazon S3. Concurrently, we can create a stream table from the data flowing in through a Kafka message stream
    2. Use a batch cluster for offline data processing. In this example, we use an Amazon EMR cluster which creates a fact table in it. It also provides a Detail Wide Data (DWD) table which has been used as a Flink dynamic table to perform consequence processing after a lookup join
      • It is typically located in the middle layer of a data warehouse, between the raw data contained in the Operational Data Store (ODS) and the highly aggregated data found in the Data Warehouse (DW), or Data Mart (DM).
      • The primary purpose of the DWD layer is to support complex data analysis and reporting needs by providing a detailed and comprehensive data view.
      • Both the fact table and DWD table are hive tables on Hadoop
    3. Use a streaming cluster for the real-time processing. In this example, we use an Amazon EMR cluster to stream event ingestion and analyze it using Flink, using Flink Kafka connector and Hive connector to join the streaming event data and statics dimension data (fact table)

    One of the key challenges encountered with this approach is related to the management of the lookup dimension table data. Initially, when the Flink application is started, this data is stored in the task manager’s state. However, during subsequent operations like continuous queries or window aggregations, the dimension table data isn’t automatically refreshed. This means that the operator must either restart the Flink application periodically or manually refresh the dimension table data in the temporary table. This step is crucial to ensure that the join operations and aggregations are always performed with the most current dimension data.

    Another significant challenge with this approach is needing to pull the entire dimension table data and perform a cold start each time. This becomes particularly problematic when dealing with a large volume of dimension table data. For instance, when handling tables with tens of millions of registered users or tens of thousands of product SKU attributes, this process generates substantial input/output (IO) overhead. Consequently, it leads to performance bottlenecks, impacting the efficiency of the system.

    Flink’s checkpointing mechanism processes the data and stores checkpoint snapshots of all the states during continuous queries or window aggregations, resulting in state snapshots data bloat.

    Optimizing the solution

    This post includes an optimized solution to address the aforementioned challenges, by automatically loading Hive dimension table data into the Alluxio UFS via the Alluxio cache layer. We join this data with Flink’s temporal joins to create a view on a changing table. This view reflects the content of a table at a specific point in time

    Alluxio is a distributed cache engine for big data technology stacks. It provides a unified UFS that can connect to the underlying Amazon S3 and HDFS data. Alluxio UFS read and write operations warm up the distributed storage layers on S3 and HDFS and thus significantly increase throughput and reducing network overhead. Deeply integrated with upper level computing engines such as Hive, Spark, and Trino, Alluxio is an excellent cache accelerator for offline dimension data.

    Additionally, we utilize Flink’s temporal table function to pass a time parameter. This function returns a view of the temporal table at the specified time. By doing so, when the main table of the real-time dynamic table is correlated with the temporal table, it can be associated with a specific historical version of the dimension data

    Solution implementation details

    For this post, we use “user behavior” log data in Kafka as real-time stream fact table data, and user information data on Hive as offline dimension table data. A demo with Alluxio + Flink temporal join is used to verify the Flink join optimized solution.

    Real-time fact tables

    For this demonstration, we utilize user behavior JSON data simulated by the open-source component json-data-generator. We write the data to Amazon Managed Kafka (Amazon MSK) in real-time. Using the Flink Kafka Connector, we convert this stream into a Flink stream table for continuous queries. This served as our fact table data for real-time joins.

    A sample of the user behavior simulation data in JSON format is as follows:

    [{          
    	"timestamp": "nowTimestamp()",
    	"system": "BADGE",
    	"actor": "Agnew",
    	"action": "EXIT",
    	"objects": ["Building 1"],
    	"location": "45.5,44.3",
    	"message": "Exited Building 1"
    }]
    

    It includes user behavior information such as operation time, login system, user signature, behavioral activities, and service objects, locations, and related text fields. We create a fact table in Flink SQL with the main fields as follows:

    CREATE TABLE logevent_source (`timestamp`  string, 
    `system` string,
     actor STRING,
     action STRING
    ) WITH (
    'connector' = 'kafka',
    'topic' = 'logevent',
    'properties.bootstrap.servers' = 'b-6.msk06.dr04w4.c3.kafka.ap-southeast-1.amazonaws.com:9092,b-5.msk06.dr04w4.c3.kafka.ap-southeast-1.amazonaws.com:9092,b-1.msk06.dr04w4.c3.kafka.ap-southeast-1.amazonaws.com:9092 (http://b-6.msk06.dr04w4.c3.kafka.ap-southeast-1.amazonaws.com:9092%2Cb-5.msk06.dr04w4.c3.kafka.ap-southeast-1.amazonaws.com:9092%2Cb-1.msk06.dr04w4.c3.kafka.ap-southeast-1.amazonaws.com:9092/)',
    'properties.group.id' = 'testGroup6',
    'scan.startup.mode'='latest-offset',
    'format' = 'json'
    );

    Caching dimension tables with Alluxio

    Amazon EMR provides solid integration with Alluxio. You can use the Amazon EMR bootstrap startup script to automatically deploy Alluxio components and start the Alluxio master and worker processes when an Amazon EMR cluster is created. For detailed installation and deployment steps, refer to the article Integrating Alluxio on Amazon EMR.

    In an Amazon EMR cluster that integrates Alluxio, you may use Alluxio to create a cache table for the Hive offline dimension table as follows:

    ##Set up the client jar package in hive-env.sh:
    $ export HIVE_AUX_JARS_PATH=/<PATH_TO_ALLUXIO>/client/alluxio-2.2.0-client.jar:${HIVE_AU
    
    ##Make sure the UFS is configured on the EMR cluster where Alluxio is installed and that the table/db path has been created:
    alluxio fs mkdir alluxio://ip-xxx-xxx-xxx-xxx.ap-southeast-1.compute.internal:19998/s3/customer
    alluxio fs chown hadoop:hadoop alluxio://ip-xxx-xxx-xxx-xxx.ap-southeast-1.compute.internal:19998/s3/customer
    
    ##On the AWS EMR cluster, create a Hive table path pointing to Alluxio namespace URI:
    !connect jdbc:hive2://xxx.xxx.xxx.xxx:10000/default;
    hive> CREATE TABLE customer(
        c_customer_sk             bigint,
        c_customer_id             string,
        c_current_cdemo_sk        bigint,
        c_current_hdemo_sk        bigint,
        c_current_addr_sk         bigint,
        c_first_shipto_date_sk    bigint,
        c_first_sales_date_sk     bigint,
        c_salutation              string,
        c_first_name              string,
        c_last_name               string,
        c_preferred_cust_flag     string,
        c_birth_day               int,
        c_birth_month             int,
        c_birth_year              int,
        c_birth_country           string,
        c_login                   string,
        c_email_address           string
    )
        ROW FORMAT DELIMITED
        FIELDS TERMINATED BY '|'
        STORED AS TEXTFILE
        LOCATION 'alluxio://ip-xxx-xxx-xxx-xxx.ap-southeast-1.compute.internal:19998/s3/customer';
    OK
    Time taken: 3.485 seconds

    As shown in the previous section, the Alluxio table location alluxio://ip-xxx-xx:19998/s3/customer points to the S3 path where the Hive dimension table is located; writing to the customer dimension table is automatically synchronized to the Alluxio cache.

    After creating the Alluxio Hive offline dimension table, you can view the details of the Alluxio cache table by connecting to the Hive metadata through the Hive catalog in Flink SQL:

    CREATE CATALOG hiveCatalog WITH (  'type' = 'hive',
        'default-database' = 'default',
        'hive-conf-dir' = '/etc/hive/conf/',
        'hive-version' = '3.1.2',
        'hadoop-conf-dir'='/etc/hadoop/conf/'
    );
    -- set the HiveCatalog as the current catalog of the session
    USE CATALOG hiveCatalog;
    show create table customer;
    create external table customer(
        c_customer_sk             bigint,
        c_customer_id             string,
        c_current_cdemo_sk        bigint,
        c_current_hdemo_sk        bigint,
        c_current_addr_sk         bigint,
        c_first_shipto_date_sk    bigint,
        c_first_sales_date_sk     bigint,
        c_salutation              string,
        c_first_name              string,
        c_last_name               string,
        c_preferred_cust_flag     string,
        c_birth_day               int,
        c_birth_month             int,
        c_birth_year              int,
        c_birth_country           string,
        c_login                   string,
        c_email_address           string
    ) 
    row format delimited fields terminated by '|'
    location 'alluxio://ip-xxx-xxx-xxx-xxx.ap-southeast-1.compute.internal:19998/s3/30/customer' 
    TBLPROPERTIES (
      'streaming-source.enable' = 'false',  
      'lookup.join.cache.ttl' = '12 h'
    )

    As shown in the preceding code, the location path of the dimension table is the UFS cache path Uniform Resource Identifier (URI). When the business program reads and writes the dimension table, Alluxio automatically updates the customer dimension table data in the cache and asynchronously writes it to the Alluxio backend storage path of the S3 table to achieve table data synchronization in the data lake.

    Flink temporal table join

    Flink temporal table is also a type of dynamic table. Each record in the temporal table is correlated with one or more time fields. When we join the fact table and the dimension table, we usually need to obtain real-time dimension table data for the lookup join. Thus, when creating or joining a table, we usually need to use the proctime() function to specify the time field of the fact table. When we join the tables, we use the syntax of FOR SYSTEM_TIME AS OF to specify the time version of the fact table that corresponds to the time of the lookup dimension table.

    For this post, the customer information is a changing dimension table in the Hive offline table, whereas the customer behavior is the fact table in Kafka. We specified the time field with proctime() in the Flink Kafka source table. Then when joining the Flink Hive table, we used FOR SYSTEM_TIME AS OF to specify the time field of the lookup Kafka source table to allow us to realize the Flink temporal table join operation

    As shown in the following code, a fact table of user behavior is created through the Kafka Connector in Flink SQL. The ts field refers to the timestamp when the temporal table is joined:

    CREATE TABLE logevent_source (`timestamp`  string, 
    `system` string,
     actor STRING,
     action STRING,
     ts as PROCTIME()
    ) WITH (
    'connector' = 'kafka',
    'topic' = 'logevent',
    'properties.bootstrap.servers' = 'b-6.msk06.dr04w4.c3.kafka.ap-southeast-1.amazonaws.com:9092,b-5.msk06.dr04w4.c3.kafka.ap-southeast-1.amazonaws.com:9092,b-1.msk06.dr04w4.c3.kafka.ap-southeast-1.amazonaws.com:9092 (http://b-6.msk06.dr04w4.c3.kafka.ap-southeast-1.amazonaws.com:9092%2Cb-5.msk06.dr04w4.c3.kafka.ap-southeast-1.amazonaws.com:9092%2Cb-1.msk06.dr04w4.c3.kafka.ap-southeast-1.amazonaws.com:9092/)',
    'properties.group.id' = 'testGroup-01',
    'scan.startup.mode'='latest-offset',
    'format' = 'json'
    );

    The Flink offline dimension table and the streaming real-time table are joined as follows:

    select a.`timestamp`,a.`system`,a.actor,a.action,b.c_login from 
           (select *, proctime() as proctime from user_logevent_source) as a 
     left join customer  FOR SYSTEM_TIME AS OF a.proctime as b on a.actor=b.c_last_name;

    When the fact table logevent_source joins the lookup dimension table, the proctime function ensures real-time joins by obtaining the latest dimension table version. This dimension data, cached in Alluxio, delivers significantly better read performance than direct S3 access.

    At the same time, the dimension table data is already cached in Alluxio; the read performance is much better than offline data read on S3.

    The comparison test shows that Alluxio cache brings a clear performance advantage by switching the S3 and Alluxio paths of the customer dimension table through Hive

    You can easily switch the local and cache location paths with alter table in hive cli:

    alter table customer set location "s3://xxxxxx/data/s3/30/customer";
    alter table customer  set location "alluxio://ip-xxx-xxx-xxx-xxx.ap-southeast-1.compute.internal:19998/s3/30/customer";

    You can also select the Task Manager log from the Flink dashboard for a split test.

    The performance of the fact table load was doubled through the implementation of optimized data processing techniques.

    1. Before caching (S3 path read): 5s load time
      2022-06-29 02:54:34,791 INFO  com.amazon.ws.emr.hadoop.fs.s3n.S3NativeFileSystem           [] - Opening 's3://salunchbucket/data/s3/30/customer/data-m-00029' for reading
      2022-06-29 02:54:39,971 INFO  org.apache.flink.table.filesystem.FileSystemLookupFunction   [] - Loaded 433000 row(s) into lookup join cache

    2. After caching (Alluxio read): 2s load time
      2022-06-29 03:25:14,476 INFO  com.amazon.ws.emr.hadoop.fs.s3n.S3NativeFileSystem           [] - Opening 's3://salunchbucket/data/s3/30/customer/data-m-00029' for reading
      2022-06-29 03:25:16,397 INFO  org.apache.flink.table.filesystem.FileSystemLookupFunction   [] - Loaded 433000 row(s) into lookup join cache

    The timeline on JobManager clearly shows the difference in execution duration under Alluxio and S3 paths.

    For single task query ,we accelerate by more than 1 times using this solution. The overall job performance improvement is even more visible.

    Other optimalizations to consider

    Implementing a continuous join requires pulling dimension data every time. Does it lead to Flink’s checkpoint state bloat that can cause Flink TaskManager RocksDB to explode or memory overflow.
    In Flink, the state comes with a TTL mechanism. You can set a TTL expiration policy to trigger Flink to clean up expired state data. Flink SQL can be set using the hint method.

    insert into logevent_sink
    select a.`timestamp`,a.`system`,a.actor,a.action,b.c_login from 
    (select *, proctime() as proctime from logevent_source) as a 
      left join 
    customer/*+ OPTIONS('lookup.join.cache.ttl' = '5 min')*/  FOR SYSTEM_TIME AS OF a.proctime as b 
    on a.actor=b.c_last_name;

    Flink Table/Streaming API is similar:

    StateTtlConfig ttlConfig = StateTtlConfig
        .newBuilder(Time.days(7))
        .setUpdateType(StateTtlConfig.UpdateType.OnCreateAndWrite)
        .setStateVisibility(StateTtlConfig.StateVisibility.NeverReturnExpired)
        .cleanupInRocksdbCompactFilter() 
        .build();
    ValueStateDescriptor<Long> lastUserLogin = 
        new ValueStateDescriptor<>("lastUserLogin", Long.class);
    lastUserLogin.enableTimeToLive(ttlConfig);
    StreamTableEnvironment.getConfig().setIdleStateRetentionTime(min, max);

    Restart the lookup join after the configuration. As you can see from the Flink TM log, after TTL expires, it triggers clean-up and re-pull the Hive dimension table data:

    2022-06-29 04:17:09,161 INFO  org.apache.flink.table.filesystem.FileSystemLookupFunction   
    [] - Lookup join cache has expired after 5 minute(s), reloading

    In addition, you can reduce the number of checkpoint snapshots by configuring Flink state retention and thereby reduce the amount of space taken up by state at the time of snapshot.

    Flink job configuration as follow:
    -D state.checkpoints.num-retained=5 

    After the configuration, you can see that in the S3 checkpoint path, the Flink job automatically cleans up historical snapshots and keeps the most recent 5 snapshots, thus ensuring that checkpoint snapshots do not accumulate.

    [hadoop@ip-172-31-41-131 ~]$ aws s3 ls s3://salunchbucket/data/checkpoints/7b9f2f9becbf3c879cd1e5f38c6239f8/
                               PRE chk-3/
                               PRE chk-4/
                               PRE chk-5/
                               PRE chk-6/
                               PRE chk-7/

    Summary

    Customers implementing Flink streaming framework to join dimension and real-time fact tables frequently encounter performance challenges. In this post, we presented an optimized solution that uses Alluxio’s caching capabilities to automatically load Hive dimension table data into the UFS cache. By integrating with Flink temporal table joins, dimension tables are transformed into time-versioned views, effectively addressing performance bottlenecks in traditional implementations.


    About the author

    Jeff Tang

    Jeff Tang

    Jeff is a Data Analytics Solutions Architect at AWS. He’s responsible for designing and optimizing Amazon Data Analytic services, with over 10 years of experience in data architecture and development. Former roles include Senior Consulting Advisor at Oracle, Senior Architect at Migu Culture Data Market, and Data Analytics Architect at ANZ Bank. Extensive experience in big data, data lakes, intelligent lakehouses, and MLOps platforms

    Federate access to Amazon SageMaker Unified Studio with AWS IAM Identity Center and Ping Identity

    Post Syndicated from Raghavarao Sodabathina original https://aws.amazon.com/blogs/big-data/federate-access-to-amazon-sagemaker-unified-studio-with-aws-iam-identity-center-and-ping-identity/

    With an identity provider (IdP), you can manage your user identities outside of AWS and give these external user identities permissions to use AWS resources in your AWS accounts. External IdPs, such as Ping Identity, can integrate with AWS IAM Identity Center to be the source of truth for Amazon SageMaker Unified Studio. SageMaker Unified Studio also supports trusted identity propagation for SQL analytics, including Amazon Athena and Amazon Redshift.

    SageMaker Unified Studio provides an integrated experience to use your data and tools for analytics and AI. You can use SageMaker Unified Studio to discover your data and put it to work using familiar AWS analytics and machine learning (ML) services for model development, generative AI, big data processing, and SQL analytics, assisted by Amazon Q Developer. By default, SageMaker domains support AWS Identity and Access Management (IAM) user credentials. You can also enable access to SageMaker domains in SageMaker Unified Studio for users with single sign-on (SSO) with IAM Identity Center and direct SAML integration with SageMaker Unified Studio.

    Users can access SageMaker Unified Studio with their existing corporate credentials. With IAM Identity Center, administrators can connect their existing external IdPs and continue to manage users and groups in those existing identity systems, which can then be synchronized with IAM Identity Center using System for Cross-domain Identity Management (SCIM).In this post, we show how to set up workforce access with SageMaker Unified Studio using Ping Identity as an external IdP with IAM Identity Center.

    In this post, we show how to set up workforce access with SageMaker Unified Studio using Ping Identity as an external IdP with IAM Identity Center.

    Solution overview

    We walk through the following high-level steps to implement this solution:

    1. Enable IAM Identity Center.
    2. Create a SageMaker Unified Studio domain.
    3. Set up your IdP (for this example, Ping Identity).
    4. Connect Ping Identity and IAM Identity Center.
    5. Set up automatic provisioning of users and groups in IAM Identity Center.
    6. Configure SageMaker Unified Studio SSO user access.

    Prerequisites

    For this walkthrough, you should have the following prerequisites:

    • An AWS account with IAM Identity Center enabled. It is recommended to use an organization-level IAM Identity Center instance for best practices and centralized identity management across your AWS organization.
    • A Ping Identity account.
    • A browser with network connectivity to Ping Identity and SageMaker Unified Studio.

    Enable IAM Identity Center

    To enable IAM Identity Center, follow the instructions in Enable IAM Identity Center.

    Create a SageMaker Unified Studio domain

    To create a SageMaker Unified Studio domain, refer to the instructions in Create a Amazon SageMaker Unified Studio domain – manual setup.

    On the SageMaker console, go to the domain details and copy the Amazon Resource Name (ARN) under Domain ARN. You will use this value when you add your trust policy and when you connect your IAM IdP to your Ping Identity instance.

    Create a SageMaker Unified Studio domain

    Set up your IdP (Ping Identity)

    In this section, we walk through the procedure to set up your IdP (for this example, Ping Identity).

    Create an environment in Ping Identity

    Complete the following steps to create an environment for Ping Identity:

    1. Log in to your Ping Identity account.
    2. Choose Create Environment.
    3. Choose Create a Customer Solution.
    4. In the Tailor your experiences pop-up, choose Skip.
      Create an environment in Ping Identity

    Create a group in Ping Identity

    Complete the following steps to create a group in Ping Identity:

    1. On the Environments page, choose Manage Environments.
    2. In the navigation pane, choose Directory, then choose Groups.
    3. Choose the plus sign to add a group.
    4. For Group Name, enter sagemaker
    5. For Description, enter an optional description (for example, Amazon SageMaker Unified Studio).
    6. For Population, choose Default.
    7. Choose Save.
      Create a group in Ping Identity
    8. On the Roles tab for the sagemaker group, assign the Environment Admin role to the group.
      Assigning roles for the sagemaker group

    Create a user in Ping Identity

    Complete the following steps to create a user:

    1. In the navigation pane, choose Directory, then choose Users.
    2. Choose the plus sign to create a user.
    3. Provide values for Given name, Family name, Username, and Email.
    4. For Password, choose First time password.
    5. Choose Save.

    You can add more users as needed.

    Assign group to user

    Complete the following steps to assign your group to your user:

    1. In the navigation pane, choose Directory, then choose Groups.
    2. Choose the sagemaker group you created.
    3. On the Users tab, choose the plus sign to add a user.
    4. Add the user you created.

    Connect Ping Identity and IAM Identity Center

    To configure the integration between Ping Identity and IAM Identity Center, you need access to both management consoles. Although Ping Identity’s application catalog includes IAM Identity Center, we recommend configuring a standard SAML application for greater control over settings and attribute mappings.

    Complete the following steps:

    1. Go to the Ping Identity environment you created and choose Applications in the navigation pane.
    2. Choose the plus sign to add an application:
      1. For Application name, enter a name (for this example, we use unifiedstudio).
      2. For Description, enter an optional description.
      3. For Application Type, choose SAML Application.
      4. Choose Configure.

      Creating a SAML app integration in Ping Identity

    3. Sign in to the IAM Identity Center console as a user with administrative privileges.
    4. In the navigation pane, choose Settings to update your settings:
      1. On the Identity source tab, choose Change identity source on the Actions dropdown menu.
        Selecting identity source in AWS IAM Identity Center
      2. For Choose identity source, select External identity provider, then choose Next.

        Choosing External Identity provider in AWS IAM Identity Center

      3. In the Service provider metadata section, choose Download metadata file to download the IAM Identity Center metadata file.

        You will use this service provider metadata file in the next step when you connect Ping Identity with IAM Identity Center.

      Downloading service provider metadata from AWS IAM Identity Center

    5. Return to the Ping Identity console and the SAML application page.
    6. In the SAML Configuration section, select Import Metadata, upload the metadata file you downloaded, then choose Save.

      Importing service provider metadata into Ping Identity

    7. On the Overview tab of the application page, choose Download Metadata under Connection details to download the Ping Identity IdP metadata.
      You will use this for the SAML configuration in IAM Identity Center to set up Ping Identity as an IdP in the next step.

      Downloading Identity provider metadata from Ping Identity

    8. Return to the IAM Identity Center console and continue configuring your identity source:
      1. In the Identity provider metadata section, choose Choose file under IdP SAML metadata, upload the metadata file you downloaded from Ping Identity, then choose Next.

        Configuring Ping Identity as Identity Provider in AWS IAM Identity Center

      2. Choose Accept to accept the disclaimer.
      3. Choose Change identity source.
    9. Return to the Ping Identity console to complete the SAML configuration.
    10. On the Configuration tab, choose the edit icon to update the configuration:
      1. For Sign, choose Sign Assertion & Response.
      2. For Subject Name ID, enter urn:oasis:names:tc:SAML:1.1:nameid-format:emailAddress.
      3. For Assertion Validity Duration, enter 300.
      4. Leave the remaining values as default.

      Ping Identity SAML Configurations

    11. On the Attributes tab, choose the edit icon.
    12. Choose +Add to add two attribute mappings:
      1. Map the attribute saml-subject to Username, and leave Name format as default.
      2. Map the attribute https://aws.amazon.com/SAML/Attributes/PrincipalTag:Email to Email Address, and set Name format to Unspecified.
      3. Choose Save.

      Ping Identity SAML attributes mapping

    13. On the PingOne Policies tab, select Single Factor, then choose Save.
      This post uses single-factor authentication for demonstration purposes only. In your environments, follow your organization’s security standards and governance framework.

      Ping Identity policy configuration

    14. On the Access tab, search for the sagemaker group under Group Membership Policy, and assign the unifiedstudio SAML application to the group.
    15. Enable the application.
      Enabling Ping Identity SMAL application

    Set up automatic provisioning of users and groups from Ping Identity into IAM Identity Center

    To configure the automatic provisioning of users and groups between Ping Identity and IAM Identity Center through SCIM, you must have access to both management consoles. Complete the following steps:

    1. On the IAM Identity Center console, choose Settings in the navigation pane.
    2. In the Automatic provisioning section, choose Enable.
      Enabling automatic provisioning in AWS IAM Identity Center

      This enables automatic provisioning in IAM Identity Center and displays the necessary SCIM endpoint and access token information.

    3. In the Inbound automatic provisioning dialog box, copy the values for SCIM endpoint and Access token, then choose Close.
      You will use these values to configure provisioning in Ping Identity in the next step.

      Automatic provisioning configuration parameters in IAM Identity Center

      This completes the setup process in IAM Identity Center.

    4. Log in to the Ping Identity console.
    5. In the navigation pane, choose Integrations, then choose Provisioning.
    6. Choose the plus sign to add a new connection.
      Creating a new SCIM connection
    7. For Choose a connection type, choose Select next to Identity Store.
      Choosing connection type
    8. Provide a name (for this example, we use Identitycenter) and an optional description, then choose Next.
      Creating new connection
    9. Under Configuration Authentication, provide the following configuration:
      1. For SCIM BASE URL, enter the SCIM endpoint from IAM Identity Center.
      2. For Authentication Method, choose OAuth 2 Bearer Token.
      3. For Oauth Access Token, enter the access token from IAM Identity Center.
      4. For Auth Type Header, choose Bearer (default option).
      5. Choose Test Connection to validate the connection between Ping Identity and IAM Identity Center, then choose Next.

      Configuring authentication between Ping Identity and IAM Identity Center

    10. Under Configuration Preference, provide the following configuration:
      1. For User Filter Expression, enter userName Eq “%s”.
      2. For Group Membership Handling, select Merge.
      3. Leave the remaining settings as default and choose Save.

      SCIM connection preferences

    11. On the Provisioning tab, choose the plus sign, then choose New Rule to create a rule for the SCIM connection.
      Creating a new SCIM rule
    12. Enter a name (for this example, unifiedstudio) and an optional description, then choose Create Rule.
    13. Under the newly created rule, choose the plus sign next to Available Connections to add the connection identitycenter, then choose Save.
    14. Edit the user filter:
      1. For Attribute, choose Enabled.
      2. For Operator, choose Equals.
      3. For Value, choose true.
      4. Choose Save.

      User Filter attributes mapping

    15. Choose the edit icon next to Attribute Mapping and set the attribute mappings as shown in the following screenshot:
      1. Delete the Primary Phone attribute mapping because it’s optional in AWS. Leaving this field blank can cause Ping Identity’s SCIM connector to generate errors during user provisioning.
      2. Add a new attribute called Username under PingOne Directory and then map to displayName under Identitycenter.

      Attributes mapping between Ping Identity SCIM and AWS IAM Identity Center

    16. Under Group Provisioning, choose the sagemaker group if you want to sync all sagemaker group users with auto provisioning.
      1. In the pop-up, select I understand and want to continue, then choose Save.

      Assigning groups to SCIM rule

      Assigning groups to SCIM rule

    17. On the Provisioning page, choose the Connections tab.
    18. Enable the SCIM connection Identitycenter and rule unifiedstudio.

      Enabling the SCIM connection

      Enabling the SCIM rule

    This completes the SCIM setup process between Ping Identity and IAM Identity Center.

    Configure SageMaker Unified Studio SSO user access

    Complete the following steps to configure SSO user access to SageMaker Unified Studio for your SageMaker domain:

    1. On the SageMaker console, choose Domains in the navigation pane.
    2. Choose the domain for which you want to configure SAML user access.
    3. On the domain details page, you can find the SSO configuration in two locations:
      1. From the main domain view, choose Configure next to Configure SSO user access.
      2. Alternatively, scroll down to the User management tab and choose Configure SSO user access.

      SageMaker Unified Studio SSO configuration

    4. On the Choose user authentication method page, select IAM Identity Center, then choose Next.
      Choosing authentication
    5. For Choose user and group assignment method, choose from the following options, then choose Next:
      1. Require assignments: Users and groups must be explicitly added to the domain to gain access. This provides more granular control over who can access the domain.
      2. Do not require assignments: All authorized Ping Identity users and groups can access this domain if they have been assigned to the SAML application in Ping Identity.

      For either option, users or groups must have access to the Ping Identity SAML application (unifiedstudio in this example) to authenticate successfully.

      SageMaker Unified Studio SAML configuration

    6. On the Review and save page, review your choices and choose Save. These settings can’t be changed after you save them.
      Review and confirm SAML configuration
    7. If you’ve chosen to require assignments, use the Add users and groups section to add SAML users and groups to your domain.
      Add users and groups to SageMaker Unified Studio domain

    Now, users will be able to access SageMaker Unified Studio using the domain URL with their SSO credentials.

    You can explore different projects for your users and assign those projects based on your IdP user groups for fine-grained access controls. For example, you can create different SAML user groups based on their job function in Ping Identity, then assign those Ping Identity groups to the unifiedstudio SAML application in Ping Identity, and then assign those Ping Identity SAML groups to their respective project profiles in SageMaker Unified Studio. To assign project profiles for their respective groups, choose the Project profiles tab and choose your project profile. On the Authorized users and groups page, choose Add, then choose SSO groups. Choose Add users and groups button to complete the project profile assignment.

    Assigning a project profile to Ping Identity group

    Validate access with Ping Identity users

    Complete the following steps to validate access:

    1. On the SageMaker domain details page, choose the link for the SageMaker Unified Studio URL.
      Validating Ping Identity user access with Amazon SageMaker Unified Studio
    2. Log in with your user credentials.
      After successful login, you will be redirected to the SageMaker Unified Studio home page. Here, you can explore different projects to your users and assign those projects based on your SAML user groups for fine-grained access control.

      SAML authenticated Amazon SageMaker Unified Studio

    3. To assign an authorization policy, those Govern and then Domain units.
    4. Choose your SageMaker domain, then choose a suitable authorization policy. For this example, we choose Project creation policy.
      Amazon SageMaker unified studio authorization policies
    5. Choose Add policy grant to assign user groups or users to their respective project profiles.
      Amazon SageMaker unified studio authorization policies assignment

    You have successfully federated SageMaker Unified Studio with Ping Identity as an IdP with IAM Identity Center. You can connect to SageMaker Unified Studio by using your Ping Identity credentials.

    Clean up

    After you test out this solution, remember to delete the resources you created to avoid incurring future charges. For instructions to delete your SageMaker Unified Studio domain, refer to Delete domains. If you want to delete your Ping Identity account, reach out to Ping Identity for assistance.

    Conclusion

    In this post, we demonstrated how to set up Ping Identity as an IdP over SAML authentication for SageMaker Unified Studio access through IAM Identity Center federation. To learn more, refer to the Amazon SageMaker Unified Studio User Guide, which provides guidance on how to build data and AI applications using SageMaker.


    About the authors

    Raghavarao Sodabathina

    Raghavarao Sodabathina

    Raghavarao is a Principal Solutions Architect at AWS, focusing on data analytics, AI/ML, and cloud security. He engages with customers to create innovative solutions that address customer business problems and accelerate the adoption of AWS services. In his spare time, Raghavarao enjoys spending time with his family, reading books, and watching movies.

    Matt Nispel

    Matt Nispel

    Matt is an Enterprise Solutions Architect at AWS. He has more than 10 years of experience building cloud architectures for large enterprise companies. At AWS, Matt helps customers rearchitect their applications to take full advantage of the cloud. Matt lives in Minneapolis, Minnesota, and in his free time enjoys spending time with friends and family.

    Himanshu Sarda

    Himanshu Sarda

    Himanshu is a Solutions Architect at AWS who specializes in generative AI and autonomous agent architectures, helping enterprise customers revolutionize their businesses through cutting-edge AI solutions. When not pioneering AI innovations, Himanshu recharges by exploring the outdoors and creating memories with family and friends.

    Nicholaus Lawson

    Nicholaus Lawson

    Nicholaus is a Solutions Architect at AWS and part of the AI/ML specialty group. He has a background in software engineering and AI research. Outside of work, Nicholaus is often coding, learning something new, or woodworking.

    Krupanidhi Jay

    Krupanidhi Jay

    Krupanidhi is a Boston-based Enterprise Solutions Architect at AWS. He is a seasoned architect with over 20 years of experience in helping customers with digital transformation and delivering seamless digital user experiences. He enjoys working with customers to help them build scalable, cost-effective solutions in AWS. Outside of work, Jay enjoys spending time with family and traveling.

    Explore scaling options for AWS Directory Service for Microsoft Active Directory

    Post Syndicated from Nahuel Benavidez original https://aws.amazon.com/blogs/security/explore-scaling-options-for-aws-directory-service-for-microsoft-active-directory/

    You can use AWS Directory Service for Microsoft Active Directory as your primary Active Directory Forest for hosting your users’ identities. Your IT teams can continue using existing skills and applications while your organization benefits from the enhanced security, reliability, and scalability of AWS managed services. You can also run AWS Managed Microsoft AD as a resource forest. In this configuration, AWS Managed Microsoft AD serves supported AWS services while users’ identities remain under exclusive control of your organization on a self-managed Active Directory. As your organization grows and scales, so will your AWS Managed Microsoft AD deployments.

    In this post, you’ll learn how to use Amazon CloudWatch dashboards to monitor key performance metrics of your AWS Managed Microsoft AD deployment to track and analyze a directory’s performance over time. You can then use that information to determine when and how best to scale directory services for optimal performance.

    Scaling your Active Directory

    When you deploy AWS Managed Microsoft AD, the service initially creates two domain controller instances in two separate subnets of the same virtual private cloud (VPC). This architecture economically provides resiliency and high availability with a minimal set of resources. This initial configuration enables every feature that AWS Managed Microsoft AD offers. As your organization grows, its workflows will become larger and more complex, requiring that you scale your directories accordingly. AWS Managed Microsoft AD simplifies and makes the scaling process secure with minimal administrative effort. When it’s time to scale a directory, AWS Managed Microsoft AD offers two options: scale-up or scale-out.

    Understanding scale-up and scale-out

    Scale-up—also called upgrading your AWS Managed Microsoft AD—means changing the edition of an AWS Managed Microsoft AD from Standard to Enterprise. Enterprise Edition delivers larger domain controller instances, with higher compute capacity and larger storage for Active Directory objects. When a directory scales up, it retains the same number of domain controller instances that it previously had with larger quotas. Instances are replaced one at a time to minimize disruptions to production workflows.

    A few features offered by the service are a better fit for the size and compute power of Enterprise Edition AWS Managed Microsoft AD and so are only available in Enterprise Edition. Consider scaling-up your directory if you encounter any of the following scenarios:

    • You plan to replicate your directory across multiple AWS Regions. Multi-Region replication is only available in Enterprise Edition.
    • The number of Active Directory objects in the directory will exceed the recommended threshold of 30,000 objects for Standard Edition. Enterprise Edition can accommodate up to 500,000 directory objects.
    • You plan to share your directory with more than 25 other AWS accounts. The default directory sharing quota is 25 accounts for Standard Edition and 500 for Enterprise Edition.

    Important: Scaling up a directory from Standard to Enterprise is a one-way operation that cannot be reverted and operates at a higher hourly price.

    Scale-out means deploying additional domain controllers for your AWS Managed Microsoft AD. You can scale out both Standard or Enterprise directories and can scale out different Regions independently. You don’t need to scale every Region to the same number of domain controller instances. When scale-out takes place, additional domain controller instances with the same compute resources and storage capacity as existing ones are launched in the same subnets.

    Because some operations cannot be reverted, it’s important to understand the impact of each scaling operation. It’s preferable to scale out the number of domain controllers first, because you can revert that change if necessary. Consider scaling up first only if you need a feature that’s only available in Enterprise Edition.

    Making an informed decision using CloudWatch

    Since December 2021, AWS Managed Microsoft AD helps optimize scaling decisions with directory metrics in Amazon CloudWatch. Amazon CloudWatch metrics are a time-ordered set of data-points about performance indicators of a system that you can use to monitor and analyze performance over time. Metrics are stored as a time-series set and each data point has an associated timestamp. By using CloudWatch, you can create alarms based on metrics and visualize and analyze metrics to derive new insights.

    To understand the performance of a directory over time, define the key performance metrics based on your workload when you create the directory. Record the initial values of those metrics to create a performance baseline. Periodically revisit and compare data points for the same metrics to understand trends and use of resources over time. Based on the information provided by the performance baseline and periodic follow-ups, you can decide when to scale your directory and what scaling method to use. This process is depicted in Figure 1.

    Figure 1: Decision-making process for scaling an Active Directory implementation

    Figure 1: Decision-making process for scaling an Active Directory implementation

    Depending on the characteristics of your workload, you might face different resource constraints in your directory system. From an infrastructure perspective, the more commonly demanded resources are:

    • Network Interface: Current Bandwidth
    • Processor: % Processor Time
    • LogicalDisk: % Free Space

    From an Active Directory perspective, consider metrics such as:

    • NTDS: LDAP Searches/sec
    • NTDS: ATQ Estimated Queue Delay

    The following table is an example decision matrix based on which resource is constrained.

    Constrained resource Recommended action
    % Processor Time Scale out
    I/O Database Reads Average Latency Scale out
    Committed Bytes in Use Scale out
    % Free Space Scale up

    For example, you can create a CloudWatch alarm that will trigger when Processor: % Processor Time is over 80% for more than 5 minutes. If this alarm triggers often, it could be a signal that domain controller instances are struggling to service the regular volume of user authentication requests. In such a scenario, you might consider scaling-out an additional domain controller to guarantee the service’s SLA. Conversely, if the LogicalDisk: % Free Space drops below 10% and trends downwards, you might consider scaling-up to Enterprise Edition, because it provides a larger capacity for directory objects.

    To facilitate tracking and analyzing performance of AWS Managed Microsoft AD over time, you can use Amazon CloudWatch to create a custom dashboard including relevant metrics.

    Prerequisites

    Before you get started, make sure that you have the following prerequisites in place:

    Create a CloudWatch dashboard

    With the prerequisites in place, you’re ready to create a CloudWatch dashboard to track directory service metrics. For more information, see Getting started with CloudWatch automatic dashboards.

    To create a dashboard:

    1. Open the AWS Management Console for CloudWatch.
    2. In the navigation pane, choose Dashboards, and then choose Create dashboard.
    3. In the Create new dashboard dialog box, enter a name for the dashboard and then choose Create dashboard.
    4. When the Add widget window appears:
      1. Under Data sources types, select CloudWatch.
      2. Under Data type, select Metrics.
      3. Under Widget type, select Line.
      4. Choose Next.
    5. In the Add metric graph window, choose DirectoryService and then select Processor as the Metric category and % Processor Time under Metric name. Select each instance of the metric, represented as the Domain Controller IP, for one Directory ID.
    6. Choose Create widget.

      Note: if there are multiple directories in the same Region, all instances (domain controllers IPs) will be available for selection. To help ensure effective monitoring and alarms, create a separate dashboard for each directory.

    7. Choose the plus sign (+) at the top of the window to add more widgets. Repeat steps 1–6 to add additional widgets for other relevant metrics. In this example the metric categories and names added are:
      • Processor: % Processor Time
      • LogicalDisk: % Free Space
      • Memory: Committed Bytes in Use
      • Database: I/O Database Reads Average Latency
      • Network Interface: Current Bandwidth
      • DNS: Recursive Queries/Sec
    8. After adding the desired metrics, choose Save.
    Figure 2: CloudWatch dashboard showing directory services metrics

    Figure 2: CloudWatch dashboard showing directory services metrics

    (Optional) Create an alarm in CloudWatch

    Now that you have a dashboard where you can view metrics, consider setting up CloudWatch alarms to alert you when a metric reaches or goes beyond a specified threshold. For more information, see Create a CloudWatch alarm based on a static threshold and Adding an alarm to a CloudWatch dashboard.

    The following are recommended thresholds to monitor when determining the need to scale an AWS Managed Microsoft AD. These are general recommendations based on standard use cases. You might have to adjust these thresholds to make the best scaling decisions for your organization.

    • Processor: % Processor Time: Monitor CPU utilization to understand computational demands on your domain controllers. Set CloudWatch alarms at 80% for a period of 5 minutes. Sustained high values indicate potential sizing issues that might require scaling out your directory.
    • LogicalDisk: % Free Space: Maintain at least 25% free space on volumes containing Active Directory data for optimal performance. Set CloudWatch alarms to trigger when free space drops below 20%. Low disk space can severely impact directory operations and require implementing cleanup procedures or scaling up the directory.
    • Network Interface: Current Bandwidth: Average network utilization should be kept below 50% of available bandwidth during peak operations for optimal directory responsiveness. Set CloudWatch alarms at 70% utilization to allow room for spikes in activity. Consistently high values suggest network constraints that might require scaling out your directory.
    • Memory: Committed Bytes in Use: Monitor memory commitment levels to help ensure that your domain controllers have sufficient memory resources for Active Directory operations. This metric tracks the amount of virtual memory that has been committed, indicating the total memory load on your domain controllers. Set CloudWatch alarms at 80% of the commit limit. Sustained high values can lead to excessive paging, significantly degrading directory performance and potentially causing authentication delays.
    • Database: I/O Database Reads Average Latency: Maintain average read latencies below 25 milliseconds. Set CloudWatch alarms at a threshold of 50 milliseconds. If read latencies are consistently elevated, consider scaling-out your directory.
    • DNS: Recursive Queries/sec: Given the tight integration of Active Directory with DNS, monitor this metric for stability and predictable patterns. Use CloudWatch anomaly detection rather than fixed thresholds to identify unexpected behaviors that could indicate DNS configuration issues or potential security concerns.

    Post-scaling considerations

    Different resources across your architecture might contain references to the IP addresses of the AWS Managed Microsoft AD. After a scale-out operation that deploys additional domain controller instances on a directory, update existing references to maintain full functionality of workloads. References for the directory’s IP addresses can be found (but might not be limited to) the following services:

    To maintain the full functionality of your workloads after a directory scaling operation, update the following:

    • Firewall rules that allow traffic to and from the IP addresses of domain controller instances
    • Route53 Resolver endpoint rules and DNS conditional forwarders that forward queries to the directory instances
    • CloudWatch dashboards that display metric data about the directory to include dimensions for the new IP addresses

    Clean up resources

    In this post, you created components that generate costs. Clean up these resources when no longer required to avoid additional charges.

    • Remove added domain controller’s IP addresses from firewall rules, resolver endpoint rules and DNS conditional forwarders.
    • Delete the custom CloudWatch dashboards you don’t plan to keep.
    • Scale back existing directories to the previous number of domain controller instances.

    Conclusion

    In this post, you learned how to monitor directory performance metrics using Amazon CloudWatch. By combining performance baselines, monitoring, and planning, you can make informed decisions about when and how to scale a directory safely and efficiently. By scaling directories in a timely manner, you can optimize efficiency and reduce the risk of outages by having a right-sized directory service to support your organization’s workloads.

    Scale out your directory when your Active Directory-aware workflows have grown over time and the solution requires additional domain controller instances to maintain the service SLA. Scale up your directory when you require a feature that’s only available in Enterprise Edition AWS Managed Microsoft AD, such as multi-Region replication or additional storage to accommodate Active Directory objects. By using the flexible scaling capabilities and independent Regional expansion, you can optimize costs while maintaining appropriate service levels.

    To learn more about AWS Managed Microsoft AD optimization and monitoring with Amazon CloudWatch, see:

    Nahuel Benavidez
    Nahuel Benavidez

    Nahuel is a Sr. CSE in AWS, specializing in AWS Directory Service, Microsoft Technologies, and SQL Server. He enjoys teaming with customers to discover exciting ways to explore AWS services. Nahuel loves to spoil his niece and goddaughters above all else. Also, Dungeons and Dragons (before it was popular), CrossFit, hiking, trekking and, sharing a pint with friends but
    “just one.”

    Build a trusted foundation for data and AI using Alation and Amazon SageMaker Unified Studio

    Post Syndicated from Anthony Lempelius, James Mesney original https://aws.amazon.com/blogs/big-data/build-a-trusted-foundation-for-data-and-ai-using-alation-and-amazon-sagemaker-unified-studio/

    This post was co-written with Anthony Lempelius and James Mesney from Alation.

    When a team wants to reuse a dataset, whether it is to build a new pipeline, launch a dashboard, run an analysis, or power an AI application, the first challenge is rarely the code. Data engineers need to understand lineage, transformations, and operational expectations. Data analysts and BI engineers need consistent definitions, metrics, and trusted sources. Data scientists and AI engineers need to know provenance, quality, access constraints, and how data or features were derived. In many organizations, that context is captured in different places by different teams, often across solutions like Alation and SageMaker Unified Studio, both of which can serve as a system of record for business context depending on who is doing the work and where they operate day to day. When those perspectives are not connected, people revalidate the same information, debate definitions, and duplicate documentation across tools. A unified metadata foundation brings these role specific views together so business context, technical metadata, and governance stay aligned across platforms, making data easier to trust, easier to find, and easier to use across analytics and AI.

    The new Alation integration with Amazon SageMaker Unified Studio addresses these challenges by synchronizing catalog metadata between both systems. This synchronization creates a unified metadata experience where technical teams working in SageMaker Unified Studio and business teams working in Alation collaborate on top of the same metadata. You can verify how ML and analytics assets are created, understand dependencies, and maintain traceability across your data lifecycle regardless of which system your teams prefer to use.

    In this post, we demonstrate who benefits from this integration, how it works, the specific metadata it synchronizes, and provide a complete deployment guide for your environment.

    The value of unified metadata governance

    Organizations managing large-scale analytics and ML workloads face critical challenges when metadata is fragmented across multiple systems. When metadata exists in silos, data scientists spend valuable time searching for the right datasets. Teams duplicate metadata management efforts, creating inconsistent definitions and conflicting metrics across the organization.

    Regulatory requirements demand clear provenance. Without unified metadata governance, organizations struggle to demonstrate compliance, trace data origins, and maintain audit trails across their ML and analytics pipelines. Data discovery becomes a bottleneck when teams can’t quickly find, understand, and trust the data they need, delaying model development and reducing the overall business value of data investments.

    Applying consistent governance policies across disparate systems is nearly impossible without a unified metadata layer. This creates security vulnerabilities, data quality issues, and compliance blind spots. A unified metadata governance approach alleviates these challenges by providing a single source of truth for metadata across ML and analytics systems, enabling faster data discovery, consistent governance, and confident compliance while reducing the operational burden on data and ML teams.

    Solution overview

    The Alation and SageMaker Unified Studio integration unifies the user experience, synchronizing metadata from cataloged assets between both systems.

    This Phase 1 integration extracts metadata from Amazon SageMaker Catalog into Alation, giving you one place to discover assets.

    The integration connects through AWS Identity and Access Management (IAM) authentication and synchronizes key metadata elements, including domains, projects, asset names, descriptions, owners, glossary terms, and custom metadata fields. Every metadata update includes provenance information: the originating service, the person who made the change, and the timestamp, creating comprehensive audit trails for compliance.

    You can run metadata extractions on demand or schedule them to run automatically. The system performs an initial bulk extraction of your selected domains and projects, then keeps it up-to-date through incremental updates using either event-driven triggers or scheduled polling. Communication uses encrypted APIs with scoped IAM permissions following least-privilege principles.

    This integration helps organizations in financial services, telecommunications, retail, manufacturing, and transportation that manage large numbers of analytics and ML workloads across many systems and teams. You can reduce metadata duplication, accelerate data discovery, and enable your data scientists, analysts, and engineers to find trusted data faster so they can focus on building insights rather than validating data quality.

    The following diagram illustrates the solution architecture.

    The following screenshot showcases the Alation catalog displaying the SageMaker Unified Studio project and its synchronized assets.

    Metadata synchronization

    This integration automatically synchronizes essential metadata between SageMaker Unified Studio and Alation, facilitating consistent information across both systems. The synchronization brings together the types of metadata you need for discovery, governance, and audit workflows, giving you clearer insight into how datasets, features, and models relate across your services.

    The integration synchronizes catalog metadata, including domains, projects, asset names, descriptions, owners, glossary terms, and metadata forms. Additionally, the integration synchronizes provenance metadata, which includes information about the originating service, the actor who made the change, and the timestamp, to support traceability and audit workflows.

    Integration mechanics

    The integration connects SageMaker Unified Studio and Alation through a scoped IAM role that provides secure, encrypted communication. After you configure this connection within Alation, the system performs an initial extraction of your selected domains and projects, then keeps information current through incremental updates using either event-driven triggers or scheduled polling.

    The integration synchronizes metadata forms from SageMaker Unified Studio into Alation through automated field mapping between both systems’ schemas. Metadata forms can capture various asset specific details like feature store references, training run identifiers, model versions, and evaluation metrics.

    Every metadata update includes provenance information: the originating service, the person who made the change, and when it occurred. This supports audit and stewardship workflows. Access controls follow least-privilege principles through IAM while applying Alation’s role-based permissions, letting you limit synchronization by project, namespace, or tag as needed.

    Security and compliance

    Security and compliance are critical when synchronizing metadata across systems. This integration follows enterprise security practices to facilitate safe, controlled metadata synchronization. The connector uses least-privilege access, encrypted transport, and clear separation between metadata and data, so you can maintain governance without disrupting existing workflows.

    You configure a scoped IAM role to define which accounts, projects, and namespaces the connector can access, making sure access follows your organization’s security policies. Metadata moves over TLS-protected APIs, and you control which domains and projects to include in Alation. By default, the integration synchronizes only metadata; your data files and artifacts remain in their original AWS locations unless you explicitly choose to export them.

    Alation maintains a complete audit trail by recording extraction events, mapping changes, and stewardship activities. These security controls support compliant metadata governance while preserving your existing operational practices.

    Prerequisites

    Before setting up this integration, ensure you have the following:

    • An Alation Cloud Service (ACS) instance
    • Alation server admin access
    • An AWS account
    • A SageMaker Unified Studio domain and project with existing metadata

    Configure authentication

    Before configuring the Alation connector, you must set up the required AWS resources and permissions. The first step is to configure authentication. The Alation connector supports two authentication methods to access SageMaker Unified Studio. Choose the method that best fits your security requirements.

    Option 1: IAM role (Recommended)

    Create an IAM role that the Alation connector will assume to access SageMaker Unified Studio. For detailed instructions on creating IAM roles, see IAM role creation.

    The following is an example IAM permission policy for SageMaker Catalog access:

    {
       "Version": "2012-10-17",
        "Statement": [
            {
                "Sid": "AlationSageMakerAccess",
                "Effect": "Allow",
                "Action": [
                    "datazone:ListDomains",
                    "datazone:GetFormType",
                    "datazone:Search",
                    "datazone:ListProjects",
                    "datazone:GetAsset"
                ],
                "Resource": "arn:aws:datazone:<region>:<account-id>:domain/*”
            }
        ]
    }

    The following is an example trust policy for the IAM role:

    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Sid": "AlationSageMakerAccessAssumeRole",
                "Effect": "Allow",
                "Principal": {
                    "AWS": "<alation_provided_role_arn>"
                },
                "Action": "sts:AssumeRole"
            }
        ]
    }     

    Option 2: IAM user with access keys

    Create an IAM user with programmatic access and attach the necessary permissions. For detailed instructions on creating IAM users, see Create an IAM user in your AWS account.

    Create an IAM user with programmatic access enabled, attach the following policy, and generate access keys for use in Alation configuration:

    {
       "Version": "2012-10-17",
        "Statement": [
            {
                "Sid": "AlationSageMakerAccess",
                "Effect": "Allow",
                "Action": [
                    "datazone:ListDomains",
                    "datazone:GetFormType",
                    "datazone:Search",
                    "datazone:ListProjects",
                    "datazone:GetAsset"
                ],
                "Resource": "arn:aws:datazone:<region>:<account-id>:domain/*"
            }
        ]
    }

    Add IAM role or user to SageMaker Unified Studio domain

    Add the IAM role or user you created to the SageMaker Unified Studio domain. For detailed instructions on adding users to a domain, see User management in Amazon SageMaker Unified Studio. The following screenshot shows an example of adding IAM users on the SageMaker dashboard.

    Add IAM role or user to SageMaker Unified Studio projects

    The IAM role or user must be added as a member to all SageMaker Unified Studio projects that contain metadata you want to synchronize with Alation. Projects without this member will not be included in the synchronization process.

    Add the IAM role or user as a project member with Contributor or Owner permissions for each project you want to include in the sync, as illustrated in the following screenshot. For detailed instructions on adding project members, see Add project members.

    Install SageMaker enhanced connector

    After completing the AWS setup, you can configure the Alation connector to establish the integration. The connector is distributed as a .zip package for upload and installation in the Alation application. To obtain the connector, contact the Forward Deployed Engineering team or your Alation Account Manager.

    When you have the .zip package, follow the installation procedures to add the connector.

    Create and configure Alation’s data source

    Navigate to the Data Sources section in Alation, create a new data source, and select SageMaker Catalog as the source type. Configure the connection settings with the authentication method chosen in the AWS setup.

    For IAM role authentication, use the following configuration:

    • Connection Type: IAM Role
    • Role ARN: ARN of the IAM role created in AWS setup
    • External ID: External ID configured in the trust policy
    • AWS Region: Region where your SageMaker Unified Studio domain is located

    For IAM user authentication, use the following configuration:

    • Connection Type: Access Keys
    • Access Key ID: Access key from AWS setup
    • Secret Access Key: Secret key from AWS setup
    • AWS Region: Region where your SageMaker Unified Studio domain is located

    Test the connection to verify authentication and network connectivity, as shown in the following screenshot.

    Configure metadata extraction settings

    Configure the extraction scope by selecting the SageMaker domains and projects to synchronize, as shown in the following screenshot. Only projects where the IAM role or user is a member will be available for synchronization.

    Run initial extraction

    Execute the first metadata synchronization to import existing metadata from SageMaker Unified Studio into Alation. Monitor the extraction progress through Alation’s status indicators and validate that SageMaker assets appear correctly in the catalog.

    The following screenshot shows the job history page with job status Running.

    The following screenshot shows the job history page with job status Succeeded.

    The following screenshot shows the Alation catalog displaying the SageMaker Unified Studio project and its synchronized assets.

    Operate and tune

    Configure ongoing operations by setting extraction cadence, configuring reconciliation alerts, and monitoring logs regularly. Add data stewards to synchronized assets, and consider enabling AI-generated descriptions or working with Alation Professional Services for advanced governance design.

    Enhanced capabilities

    The next phase of the integration introduces three key capabilities: bi-directional metadata synchronization, lineage replication, and data quality metadata replication. The bi-directional capability gives you the flexibility to control where metadata updates originate, either in Alation or in SageMaker Unified Studio, so you can manage metadata changes in the service that best aligns with your organizational workflows and governance processes.

    The feature set is rolling out in phases. Phase 1 is available at the time of writing this post and provides extraction from SageMaker Unified Studio into Alation, including initial and incremental updates and audit logging. Phase 2 is coming soon and will offer configurable principal catalogs, advanced scoped syncs, and reconciliation workflows for Alation Cloud Service customers.

    These enhancements will support governed, scalable ML operations with increasing depth and automation.

    Conclusion

    The Alation and SageMaker Unified Studio integration helps organizations bridge the gap between fast analytics and ML development and the governance requirements most enterprises face. By cataloging metadata from SageMaker Unified Studio in Alation, you gain a governed, discoverable view of how assets are created and used. This supports leaders, stewards, compliance teams, and ML practitioners who depend on accurate, well-documented data to scale analytics and AI responsibly.

    To learn more about this integration and explore additional resources, refer to the Amazon SageMaker Unified Studio User Guide and Alation Documentation.


    About the authors

    Anthony Lempelius

    Anthony Lempelius

    Anthony is the Director of Channel and Alliances at Alation, where he leads strategic partnerships with independent software vendor (ISV) and systems integrator (SI) partners. He focuses on bringing joint integrations and solutions to market that help customers unlock value from trusted, well-governed data. Anthony is passionate about building the AWS Partner Network that accelerates innovation across the data and AI landscape.

    James Mesney

    James Mesney

    James is a Principal Product Manager at Alation, where he leads product strategy for advancing Alation’s Agentic capabilities. He focuses on helping organizations make their data more discoverable, governed, and actionable by shaping features that improve metadata quality, user experience, and AI-driven insights. James is passionate about building products that empower enterprises to fully unlock the value of trusted data.

    Divij Bhatia

    Divij Bhatia

    Divij is a Software Development Engineer at AWS. He is passionate about building resilient and scalable cloud-based solutions that solve real-world problems for customers. His free time often takes him outdoors, traveling and shooting landscapes.

    Leonardo Gomez

    Leonardo Gomez

    Leonardo is a Principal Analytics Specialist Solutions Architect at AWS. He has over a decade of experience in data management, helping customers around the globe address their business and technical needs.

    How to get started with security response automation on AWS

    Post Syndicated from Cameron Worrell original https://aws.amazon.com/blogs/security/how-get-started-security-response-automation-aws/

    At AWS, we encourage you to use automation. Not just to deploy your workloads and configure services, but to also help you quickly detect and respond to security events within your AWS environments. In addition to increasing the speed of detection and response, automation also helps you scale your security operations as your workloads in AWS increase and scale as well. For these reasons, security automation is a key principle outlined in the Well-Architected Framework, the AWS Cloud Adoption Framework, and the AWS Security Incident Response Guide.

    Security response automation is a broad topic that spans many areas. The goal of this blog post is to introduce you to core concepts and help you get started. You will learn how to implement automated security response mechanisms within your AWS environments. This post will include common patterns that customers often use, implementation considerations, and an example solution. Additionally, we will share resources AWS has produced in the form of the Automated Security Response GitHub repo. The GitHub repo includes scripts that are ready-to-deploy for common scenarios.

    What is security response automation?

    Security response automation is a planned and programmed action taken to achieve a desired state for an application or resource based on a condition or event. When you implement security response automation, you should adopt an approach that draws from existing security frameworks. Frameworks are published materials which consist of standards, guidelines, and best practices in order help organizations manage cybersecurity-related risk. Using frameworks helps you achieve consistency and scalability and enables you to focus more on the strategic aspects of your security program. You should work with compliance professionals within your organization to understand any specific compliance or security frameworks that are also relevant for your AWS environment.

    Our example solution is based on the NIST Cybersecurity Framework (CSF), which is designed to help organizations assess and improve their ability to help prevent, detect, and respond to security events. According to the CSF, “cybersecurity incident response” supports your ability to contain the impact of potential cybersecurity events.

    Although automation is not a CSF requirement, automating responses to events enables you to create repeatable, predictable approaches to monitoring and responding to threats. When we build automation around events that we know should not occur, it gives us an advantage over a malicious actor because the automation is able to respond within minutes or even seconds compared to an on-call support engineer.

    The five main steps in the CSF are identify, protect, detect, respond and recover. We’ve expanded the detect and respond steps to include automation and investigation activities.

    Figure 1: The five steps in the CSF

    Figure 1: The five steps in the CSF

    The following definitions for each step in the diagram above are based on the CSF but have been adapted for our example in this blog post. Although we will focus on the detect, automate and respond steps, it’s important to understand the entire process flow.

    • Identify: Identify and understand the resources, applications, and data within your AWS environment.
    • Protect: Develop and implement appropriate controls and safeguards to facilitate the delivery of services.
    • Detect: Develop and implement appropriate activities to identify the occurrence of a cybersecurity event. This step includes the implementation of monitoring capabilities which will be discussed further in the next section.
    • Automate: Develop and implement planned, programmed actions that will achieve a desired state for an application or resource based on a condition or event.
    • Investigate: Perform a systematic examination of the security event to establish the root cause.
    • Respond: Develop and implement appropriate activities to take automated or manual actions regarding a detected security event.
    • Recover: Develop and implement appropriate activities to maintain plans for resilience and to restore capabilities or services that were impaired due to a security event

    Security response automation on AWS

    AWS CloudTrail and AWS Config continuously log details regarding users and other identity principals, the resources they interacted with, and configuration changes they might have made in your AWS account. We are able to combine these logs with Amazon EventBridge, which gives us a single service to trigger automations based on events. You can use this information to automatically detect resource changes and to react to deviations from your desired state.

    Figure 2: Automated remediation flow

    Figure 2: Automated remediation flow

    As shown in the diagram above, an automated remediation flow on AWS has three stages:

    1. Monitor: Your automated monitoring tools collect information about resources and applications running in your AWS environment. For example, they might collect AWS CloudTrail information about activities performed in your AWS account, usage metrics from your Amazon EC2 instances, or flow log information about the traffic going to and from network interfaces in your Amazon Virtual Private Cloud (VPC).
    2. Detect: When a monitoring tool detects a predefined condition—such as a breached threshold, anomalous activity, or configuration deviation—it raises a flag within the system. A triggering condition might be an anomalous activity detected by Amazon GuardDuty, a resource out of compliance with an AWS Config rule, or a high rate of blocked requests on an Amazon VPC security group or AWS Web Application Firewall (AWS WAF) web access control list (web-acl).
    3. Respond: When a condition is flagged, an automated response is triggered that performs an action you’ve predefined—something intended to remediate or mitigate the flagged condition.

    Examples of automated response actions may include modifying a VPC security group, patching an Amazon EC2 instance, rotating various different types of credentials, or adding an additional entry into an IP set in AWS WAF that is part of a web-acl rule to block suspicious clients who triggered a threshold from a monitoring metric.

    You can use the event-driven flow described above to achieve a variety of automated response patterns with varying degrees of complexity. Your response pattern could be as simple as invoking a single AWS Lambda function, or it could be a complex series of AWS Step Function tasks with advanced logic. In this blog post, we’ll use two simple Lambda functions in our example solution.

    How to define your response automation

    Now that we’ve introduced the concept of security response automation, start thinking about security requirements within your environment that you’d like to enforce through automation. These design requirements might come from general best practices you’d like to follow, or they might be specific controls from compliance frameworks relevant for your business.

    Customers start with the run-books they already use as part of their Incident Response Lifecycle. Simple run-books, like responding to an exfiltrated credential, can be quickly mapped to automation especially if your run book calls for the disabling of the credential and the notification of on-call personnel. But it can be resource driven as well. Events such as a new AWS VPC being created might trigger your automation to immediately deploy your company’s standard configuration for VPC flowlog collection.
    Your objectives should be quantitative, not qualitative. Here are some examples of quantitative objectives:

    • Remote administrative network access to servers should be limited.
    • Server storage volumes should be encrypted.
    • AWS console logins should be protected by multi-factor authentication.

    As an optional step, you can expand these objectives into user stories that define the conditions and remediation actions when there is an event. User stories are informal descriptions that briefly document a feature within a software system. User stories may be global and span across multiple applications or they may be specific to a single application.

    For example:

    “Remote administrative network access to servers should have limited access from internal trusted networks only. Remote access ports include SSH TCP port 22 and RDP TCP port 3389. If remote access ports are detected within the environment and they are accessible to outside resources, they should be automatically closed and the owner will be notified.”

    Once you’ve completed your user story, you can determine how to use automated remediation to help achieve these objectives in your AWS environment. User stories should be stored in a location that provides versioning support and can reference the associated automation code.

    You should carefully consider the effect of your remediation mechanisms in order to help prevent unintended impact on your resources and applications. Remediation actions such as instance termination, credential revocation, and security group modification can adversely affect application availability. Depending on the level of risk that’s acceptable to your organization, your automated mechanism can only provide a notification which would then be manually investigated prior to remediation. Once you’ve identified an automated remediation mechanism, you can build out the required components and test them in a non-production environment.

    Sample response automation walkthrough

    In the following section, we’ll walk you through an automated remediation for a simulated event that indicates potential unauthorized activity—the unintended disabling of CloudTrail logging. Outside parties might want to disable logging to avoid detection and the recording of their unauthorized activity. Our response is to re-enable the CloudTrail logging and immediately notify the security contact. Here’s the user story for this scenario:

    “CloudTrail logging should be enabled for all AWS accounts and regions. If CloudTrail logging is disabled, it will automatically be enabled and the security operations team will be notified.”

    A note about the sample response automation below as it references Amazon EventBridge: EventBridge was formerly referred to as Amazon CloudWatch Events. If you see other documentation referring to Amazon CloudWatch, you can find that configuration now via the Amazon EventBridge console page.

    Additionally, we will be looking at this scenario through the lens of an account that has a stand-alone CloudTrail configuration. While this is an acceptable configuration, AWS recommends using AWS Organizations, which allows you to configure an organizational CloudTrail. These organizational trails are immutable to the child accounts so that logging data cannot be removed or tampered with.

    In order to use our sample remediation, you will need to enable Amazon GuardDuty and AWS Security Hub in the AWS Region you have selected. Both of these services include a 30-day trial at no additional cost. See the AWS Security Hub pricing page and the Amazon GuardDuty pricing page for additional details.

    Important: You’ll use AWS CloudTrail to test the sample remediation. Running more than one CloudTrail trail in your AWS account will result in charges based on the number of events processed while the trail is running. Charges for additional copies of management events recorded in a Region are applied based on the published pricing plan. To minimize the charges, follow the clean-up steps that we provide later in this post to remove the sample automation and delete the trail.

    Deploy the sample response automation

    In this section, we’ll show you how to deploy and test the CloudTrail logging remediation sample. Amazon GuardDuty generates the finding
    Stealth:IAMUser/CloudTrailLoggingDisabled when CloudTrail logging is disabled, and AWS Security Hub collects findings from GuardDuty using the standardized finding format mentioned earlier. We recommend that you deploy this sample into a non- production AWS account.

    Select the Launch Stack button below to deploy a CloudFormation template with an automation sample in the us-east-1 Region. You can also download the template and implement it in another Region. The template consists of an Amazon EventBridge rule, an AWS Lambda function, and the IAM permissions necessary for both components to execute. It takes several minutes for the CloudFormation stack build to complete.
    Select the Launch Stack button to launch the template

    1. In the CloudFormation console, choose the Select Template form, and then select Next.
    2. On the Specify Details page, provide the email address for a security contact. For the purpose of this walkthrough, it should be an email address that you have access to. Then select Next.
    3. On the Options page, accept the defaults, then select Next.
    4. On the Review page, confirm the details, then select Create.
    5. While the stack is being created, check the inbox of the email address that you provided in step 2. Look for an email message with the subject AWS Notification – Subscription Confirmation. Select the link in the body of the email to confirm your subscription to the Amazon Simple Notification Service (Amazon SNS) topic. You should see a success message like the one shown in Figure 3:

      Figure 3: SNS subscription confirmation

      Figure 3: SNS subscription confirmation

    6. Return to the CloudFormation console. After the Status field for the CloudFormation stack changes to CREATE COMPLETE (as shown in Figure 4), the solution is implemented and is ready for testing.
      Figure 4: CREATE_COMPLETE status

      Figure 4: CREATE_COMPLETE status

    Test the sample automation

    You’re now ready to test the automated response by creating a test trail in CloudTrail, then trying to stop it.

    1. From the AWS Management Console, choose Services > CloudTrail.
    2. Select Trails, then select Create Trail.
    3. On the Create Trail form:
      1. Enter a value for Trail name and for AWS KMS alias, as shown in Figure 5.
      2. For Storage location, create a new S3 bucket or choose an existing one. For our testing, we create a new S3 bucket.
        Figure 5: Create a CloudTrail trail

        Figure 5: Create a CloudTrail trail

      3. On the next page, under Management events, select Write-only (to minimize event volume).

        Figure 6: Create a CloudTrail trail

        Figure 6: Create a CloudTrail trail

    4. On the Trails page of the CloudTrail console, verify that the new trail has started. You should see the status as logging, as shown in Figure 7.

      Figure 7: Verify new trail has started

      Figure 7: Verify new trail has started

    5. You’re now ready to act like an unauthorized user trying to cover their tracks. Stop the logging for the trail that you just created:
      1. Select the new trail name to display its configuration page.
      2. In the top-right corner, choose the Stop logging button.
      3. When prompted with a warning dialog box, select Stop logging.
      4. Verify that the logging has stopped by confirming that the Start logging button now appears in the top right, as shown in Figure 8.

        Figure 8: Verify logging switch is off

        Figure 8: Verify logging switch is off

      You have now simulated a security event by disabling logging for one of the trails in the CloudTrail service. Within the next few seconds, the near real-time automated response will detect the stopped trail, restart it, and send an email notification. You can refresh the Trails page of the CloudTrail console to verify through the Stop logging button at the top right corner.

      Within the next several minutes, the investigatory automated response will also begin. GuardDuty will detect the action that stopped the trail and enrich the data about the source of unexpected behavior. Security Hub will then ingest that information and optionally correlate with other security events.

      Following the steps below, you can monitor findings within Security Hub for the finding type TTPs/Defense Evasion/Stealth:IAMUser-CloudTrailLoggingDisabled to be generated:

    6. In the AWS Management Console, choose Services > Security Hub.
      1. In the left pane, select Findings.
      2. Select the Add filters field, then select Type.
      3. Select EQUALS, paste TTPs/Defense Evasion/Stealth:IAMUser-CloudTrailLoggingDisabled into the field, then select Apply.
      4. Refresh your browser periodically until the finding is generated.
      Figure 9: Monitor Security Hub for your finding

      Figure 9: Monitor Security Hub for your finding

    7. Select the title of the finding to review details. When you’re ready, you can choose to archive the finding by selecting the Archive link. Alternately, you can select a custom action to continue with the response. Custom actions are one of the ways that you can integrate Security Hub with custom partner solutions.

    Now that you’ve completed your review of the finding, let’s dig into the components of automation.

    How the sample automation works

    This example incorporates two automated responses: a near real-time workflow and an investigatory workflow. The near real-time workflow provides a rapid response to an individual event, in this case the stopping of a trail. The goal is to restore the trail to a functioning state and alert security responders as quickly as possible. The investigatory workflow still includes a response to provide defense in depth and uses services that support a more in-depth investigation of the incident.

    Figure 10: Sample automation workflow

    Figure 10: Sample automation workflow

    In the near real-time workflow, Amazon EventBridge monitors for the undesired activity.

    When a trail is stopped, AWS CloudTrail publishes an event on the EventBridge bus. An EventBridge rule detects the trail-stopping event and invokes a Lambda function to respond to the event by restarting the trail and notifying the security contact via an Amazon Simple Notification Service (SNS) topic.

    In the investigative workflow, CloudTrail logs are monitored for undesired activities. For example, if a trail is stopped, there will be a corresponding log record. GuardDuty detects this activity and retrieves additional data points regarding the source IP that executed the API call. Two common examples of those additional data points in GuardDuty findings include whether the API call came from an IP address on a threat list, or whether it came from a network not commonly used in your AWS account. An AWS Lambda function responds by restarting the trail and notifying the security contact. The finding is imported into AWS Security Hub, where it’s aggregated with other findings for analyst viewing. Using EventBridge, you can configure Security Hub to export the finding to partner security orchestration tools, SIEM (security information and event management) systems, and ticketing systems for investigation.

    AWS Security Hub imports findings from AWS security services such as GuardDuty, Amazon Macie and Amazon Inspector, plus from third-party product integrations you’ve enabled. Findings are provided to Security Hub in AWS Security Finding Format (ASFF), which minimizes the need for data conversion. Security Hub correlates these findings to help you identify related security events and determine a root cause. Security Hub also publishes its findings to Amazon EventBridge to enable further processing by other AWS services such as AWS Lambda. You can also create custom actions using Security Hub. Custom actions are useful for security analysts working with the Security Hub console who want to send a specific finding, or a small set of findings, to a response or a remediation workflow.

    Deeper look into how the “Respond” phase works

    Amazon EventBridge and AWS Lambda work together to respond to a security finding.

    Amazon EventBridge is a service that provides real-time access to changes in data in AWS services, your own applications, and Software-as-a-Service (SaaS) applications without writing code. In this example, EventBridge identifies a Security Hub finding that requires action and invokes a Lambda function that performs remediation. As shown in Figure 11, the Lambda function both notifies the security operator via SNS and restarts the stopped CloudTrail.

    Figure 11: Sample “respond” workflow

    Figure 11: Sample “respond” workflow

    To set this response up, we looked for an event to indicate that a trail had stopped or was disabled. We knew that the GuardDuty finding Stealth:IAMUser/CloudTrailLoggingDisabled is raised when CloudTrail logging is disabled. Therefore, we configured the default event bus to look for this event.

    You can learn more regarding the available GuardDuty findings in the user guide.

    How the code works

    When Security Hub publishes a finding to EventBridge, it includes full details of the finding as discovered by GuardDuty. The finding is published in JSON format. If you review the details of the sample finding, note that it has several fields helping you identify the specific events that you’re looking for. Here are some of the relevant details:

    {
       …
       "source":"aws.securityhub",
       …
       "detail":{
          "findings": [{
    		…
        	“Types”: [
    			"TTPs/Defense Evasion/Stealth:IAMUser-CloudTrailLoggingDisabled"
    			],
    		…
          }]
    }
    

    You can build an event pattern using these fields, which an EventBridge filtering rule can then use to identify events and to invoke the remediation Lambda function. Below is a snippet from the CloudFormation template we provided earlier that defines that event pattern for the EventBridge filtering rule:

    # pattern matches the nested JSON format of a specific Security Hub finding
          EventPattern:
            source:
            - aws.securityhub
            detail-type:
              - "Security Hub Findings - Imported"
            detail:
              findings:
                Types:
                  - "TTPs/Defense Evasion/Stealth:IAMUser-CloudTrailLoggingDisabled"
    

    Once the rule is in place, EventBridge continuously monitors the event bus for events with this pattern.

    When EventBridge finds a match, it invokes the remediating Lambda function and passes the full details of the event to the function. The Lambda function then parses the JSON fields in the event so that it can act as shown in this Python code snippet:

    # extract trail ARN by parsing the incoming Security Hub finding (in JSON format)
    trailARN = event['detail']['findings'][0]['ProductFields']['action/awsApiCallAction/affectedResources/AWS::CloudTrail::Trail']   
    
    # description contains useful details to be sent to security operations
    description = event['detail']['findings'][0]['Description']
    

    The code also issues a notification to security operators so they can review the findings and insights in Security Hub and other services to better understand the incident and to decide whether further manual actions are warranted. Here’s the code snippet that uses SNS to send out a note to security operators:

    #Sending the notification that the AWS CloudTrail has been disabled.
    snspublish = snsclient.publish(
    	TargetArn = snsARN,
    	Message="Automatically restarting CloudTrail logging.  Event description: \"%s\" " %description
    	)
    

    While notifications to human operators are important, the Lambda function will not wait to take action. It immediately remediates the condition by restarting the stopped trail in CloudTrail. Here’s a code snippet that restarts the trail to reenable logging:

    try:
    	client = boto3.client('cloudtrail')
    	enablelogging = client.start_logging(Name=trailARN)
    	logger.debug("Response on enable CloudTrail logging- %s" %enablelogging)
    except ClientError as e:
    	logger.error("An error occured: %s" %e)
    

    After the trail has been restarted, API activity is once again logged and can be audited.

    This can help provide relevant data for the remaining steps in the incident response process. The data is especially important for the post-incident phase, when your team analyzes lessons learned to help prevent future incidents. You can also use this phase to identify additional steps to automate in your incident response.

    How to Enable Custom Action and build your own Automated Response

    Unlike how you set up the notification earlier, you may not want fully automate responses to findings. To set up automation that you can manually trigger it for specific findings, you can use custom actions. A custom action is a Security Hub mechanism for sending selected findings to EventBridge that can be matched by an EventBridge rule. The rule defines a specific action to take when a finding is received that is associated with the custom action ID. Custom actions can be used, for example, to send a specific finding, or a small set of findings, to a response or remediation workflow. You can create up to 50 custom actions.

    In this section, we will walk you through how to create a custom action in Security Hub which will trigger an EventBridge rule to execute a Lambda function for the same security finding related to CloudTrail Disabled.

    Create a Custom Action in Security Hub

    1. Open Security Hub. In the left navigation pane, under Management, open the Custom actions page.
    2. Choose Create custom action.
    3. Enter an Action Name, Action Description, and Action ID that are representative of an action that you are implementing—for example Enable CloudTrail Logging.
    4. Choose Create custom action.
    5. Copy the custom action ARN that was generated. You will need it in the next steps.

    Create Amazon EventBridge Rule to capture the Custom Action

    In this section, you will define an EventBridge rule that will match events (findings) coming from Security Hub which were forwarded by the custom action you defined above.

    1. Navigate to the Amazon EventBridge console.
    2. On the right side, choose Create rule.
    3. On the Define rule detail page, give your rule a name and description that represents the rule’s purpose (for example, the same name and description that you used for the custom action). Then choose Next.
    4. Security Hub findings are sent as events to the AWS default event bus. In the Define pattern section, you can identify filters to take a specific action when matched events appear. For the Build event pattern step, leave the Event source set to AWS events or EventBridge partner events.
    5. Scroll down to Event pattern. Under Event source, leave it set to AWS Services, and under AWS Service, select Security Hub.
    6. For the Event Type, choose Security Hub Findings – Custom Action.
    7. Then select Specific custom action ARN(s) and enter the ARN for the custom action that you created earlier.
    8. Notice that as you selected these options, the event pattern on the right was updating. Choose Next.
    9. On the Select target(s) step, from the Select a target dropdown, select Lambda function. Then, from the Function dropdown, select SecurityAutoremediation-CloudTrailStartLoggingLamb-xxxx. This lambda function was created as part of the Cloudformation template.
    10. Choose Next.
    11. For the Configure tags step, choose Next.
    12. For the Review and create step, choose Create rule.

    Trigger the automation

    As GuardDuty and Security Hub have been enabled, after AWS Cloudtrail logging is enabled, you should see a security finding generated by Amazon GuardDuty and collected in AWS Security Hub.

    1. Navigate to the Security Hub Findings page.
    2. In the top corner, from the Actions dropdown menu, select the Enable CloudTrail Logging custom action.
    3. Verify the CloudTrail configuration by accessing the AWS CloudTrail dashboard.
    4. Confirm that the trail status displays as Logging, which indicates the successful execution of the remediation Lambda function triggered by the EventBridge rule through the custom action.

    How AWS helps customers get started

    Many customers look at the task of building automation remediation as daunting. Many operations teams might not have the skills or human scale to take on developing automation scripts. Because many Incident Response scenarios can be mapped to findings in AWS security services, we can begin building tools that respond and are quickly adaptable to your environment.

    Automated Security Response (ASR) on AWS is a solution that enables AWS Security Hub customers to remediate findings with a single click using sets of predefined response and remediation actions called Playbooks. The remediations are implemented as AWS Systems Manager automation documents. The solution includes remediations for issues such as unused access keys, open security groups, weak account password policies, VPC flow logging configurations, and public S3 buckets. Remediations can also be configured to trigger automatically when findings appear in AWS Security Hub.

    The solution includes the playbook remediations for some of the security controls defined as part of the following standards:

    • AWS Foundational Security Best Practices (FSBP) v1.0.0
    • Center for Internet Security (CIS) AWS Foundations Benchmark v1.2.0
    • Center for Internet Security (CIS) AWS Foundations Benchmark v1.4.0
    • Center for Internet Security (CIS) AWS Foundations Benchmark v3.0.0
    • Payment Card Industry (PCI) Data Security Standard (DSS) v3.2.1
    • National Institute of Standards and Technology (NIST) Special Publication 800-53 Revision 5

    A Playbook called Security Control is included that allows operation with AWS Security Hub’s Consolidated Control Findings feature.

    Figure 12: Architecture of the Automated Security Solution

    Figure 12: Architecture of the Automated Security Solution

    Additionally, the library includes instructions in the Implementation Guide on how to create new automations in an existing Playbook.

    You can use and deploy this library into your accounts at no additional cost, however there are costs associated with the services that it consumes.

    Clean up

    After you’ve completed the sample security response automation, we recommend that you remove the resources created in this walkthrough example from your account in order to minimize the charges associated with the trail in CloudTrail and data stored in S3.

    Important: Deleting resources in your account can negatively impact the applications running in your AWS account. Verify that applications and AWS account security do not depend on the resources you’re about to delete.

    Here are the clean-up steps:

    Summary

    You’ve learned the basic concepts and considerations behind security response automation on AWS and how to use Amazon EventBridge, Amazon GuardDuty and AWS Security Hub to automatically re-enable AWS CloudTrail when it becomes disabled unexpectedly. Additionally you got a chance to learn about the AWS Automated Security Response library and how it can help you rapidly get started with automations through Security Hub. As a next step, you may want to start building your own custom response automations and dive deeper into the AWS Security Incident Response Guide, NIST Cybersecurity Framework (CSF) or the AWS Cloud Adoption Framework (CAF) Security Perspective. You can explore additional automatic remediation solutions on the AWS Solution Library. You can find the code used in this example on GitHub.

    If you have feedback about this blog post, submit them in the Comments section below. If you have questions about using this solution, start a thread in the
    EventBridge, GuardDuty or Security Hub forums, or contact AWS Support.

    Reduce EMR HBase upgrade downtime with the EMR read-replica prewarm feature

    Post Syndicated from Suthan Phillips original https://aws.amazon.com/blogs/big-data/reduce-emr-hbase-upgrade-downtime-with-the-emr-read-replica-prewarm-feature/

    HBase clusters on Amazon Simple Storage Service (Amazon S3) need regular upgrades for new features, security patches, and performance improvements. In this post, we introduce the EMR read-replica prewarm feature in Amazon EMR and show you how to use it to minimize HBase upgrade downtime from hours to minutes using blue-green deployments. This approach works well for single-cluster deployments where minimizing service interruption during infrastructure changes is important.

    Understanding HBase operational challenges

    HBase cluster upgrades have required complete cluster shutdowns, resulting in extended downtime while regions initialize and RegionServers come online. Version upgrades require a complete cluster switchover, with time-consuming steps that include loading and verifying region metadata, performing HFile checks, and confirming proper region assignment across RegionServers. During this critical period—which can extend to hours depending on cluster size and data volume—your applications are completely unavailable.

    The challenge doesn’t stop at version upgrades. You must regularly apply security patches and kernel updates to maintain compliance. For Amazon EMR 7.0 and later clusters running on Amazon Linux 2023, instances don’t automatically install security updates after launch; they remain at the patch level from cluster creation time. AWS recommends periodically recreating clusters with newer AMIs, requiring the same hard cutover and downtime risks as a full version upgrade. Similarly, when you need to use different instance types, traditional approaches mean taking your cluster offline.

    Solution overview

    Amazon EMR 7.12 introduces read-replica prewarm, a new feature that tackles these challenges. This feature lets you make infrastructure changes to Apache HBase on Amazon S3 at scale while reducing downtime risk and maintaining data consistency.

    With read-replica prewarm, you can prepare and validate your changes in a read-replica cluster before promoting it to active status, cutting service interruption from hours to minutes. You will learn how to prepare your read-replica cluster with the target version, execute cutover procedures that minimize downtime, and verify successful migration before completing the switchover.

    Read-replica prewarm architecture

    The following diagram shows the architecture and workflow. Both primary and read-replica clusters interact with the same Amazon S3 storage, accessing the same S3 bucket and root directory.

    Amazon EMR HBase architecture diagram showing primary cluster in Availability Zone 1 with read/write access to Amazon S3, and read-replica cluster in Availability Zone 2 with read access to S3.

    Distributed locking confirms only one HBase cluster can write at a time (for clusters version 7.12.0 and later). The read-replica cluster performs full HBase region initialization without time pressure, and after promotion, the read replica becomes the active writer as shown in the following diagram.

    Amazon EMR HBase failover scenario showing primary cluster unavailable in Availability Zone 1, with read-replica cluster in Availability Zone 2 promoted to handle read and write operations after failover.

    Implementation steps HBase cluster upgrade

    Now that you understand how read-replica prewarm works and the architecture behind it, let’s put this knowledge into practice. You will follow a process that consists of three main phases: preparation, cutover, and verification. Each phase includes specific steps, shown in the following figure, that you will execute in sequence to complete the migration.

    Process flow diagram showing three-phase HBase cluster migration: Phase 1 preparation and validation, Phase 2 cutover and DNS update, Phase 3 post-migration verification.

    Phase 1: Preparation

    Before starting the migration, prepare both your primary cluster and launch a new read-replica cluster. Each step in this phase builds toward confirming that your new cluster can properly access and serve your existing data.

    1. Run major compactions on tables to verify regions are not in SPLIT state
      Run major compactions to consolidate data files and verify regions are not in SPLIT state. Split regions can cause assignment conflicts during migration, so resolving them at the start helps maintain cluster stability throughout the transition.

      echo “major_compact 'tablename'” | hbase shell

    2. Run catalog_janitor to clean up stale regions
      Execute the catalog_janitor process (HBase’s built-in maintenance tool) to remove stale region references from the metadata. Cleaning up these references prevents confusion during region assignment in the read-replica cluster.

      echo “catalogjanitor_run” | hbase shell

    3. Confirm no inconsistencies in the primary HBase cluster
      Verify cluster integrity before migration:

      sudo -u hbase hbase hbck > hbck_report.txt

      Running the HBase Consistency Check tool version 2 (HBCK2) performs a diagnostic scan that identifies and reports problems in metadata, regions, and table states, confirming your cluster is ready for migration.

    4. Launch HBase read-replica cluster with the target version connecting to the same HBase root directory in Amazon S3 as the primary cluster
      Launch a new HBase cluster with the target version and configure it to connect to the same S3 root directory as the primary cluster. Confirm that read-only mode is enabled by default as shown in the following screenshot.

      AWS console screenshot showing Amazon EMR data durability and availability configuration options, with "Create a read-replica cluster" option selected and S3 location settings.

      If you are using AWS Command Line Interface (AWS CLI), you can enable the read replica while launching the Amazon EMR HBase on the Amazon S3 cluster by setting the hbase.emr.readreplica.enabled.v2 parameter to true in the HBase classification as shown in the following example:

      {
          "Classification": "hbase",
          "Properties": {
            "hbase.emr.readreplica.enabled.v2": "true",
            "hbase.emr.storageMode": "s3"
          }
      }

    5. Run meta refresh in this read-replica HBase cluster
      echo "refresh_meta" | hbase shell

      You’re creating a parallel environment with the new version that can access existing data without modification risk, allowing validation before committing to the upgrade.

    6. Validate the read-replica and verify that regions show OPEN status and are properly assigned:
      Execute sample read operations against your key tables to confirm the read replica can access your data correctly. In the HBase Master UI, verify that regions show OPEN status and are properly assigned to RegionServers. You should also confirm that the total data size matches your previous cluster to verify complete data visibility.
    7. Prepare for cutover on primary cluster
      Disable balancing and compactions on the primary cluster:

      echo "balance_switch false" | hbase shell
      echo "compaction_switch false" | hbase shell

      Preventing background operations from changing data layout or triggering region movements maintains a consistent state during the migration window.

      Take snapshots of your tables for rollback capability:

      # For each table
      echo "snapshot 'table_name', 'table_name_pre_migration_$(date +%Y%m%d)'" | hbase shell
      # For system tables
      echo "snapshot 'hbase:meta', 'meta_pre_migration_$(date +%Y%m%d)'" | hbase shell
      echo "snapshot 'hbase:namespace', 'namespace_pre_migration_$(date +%Y%m%d)'" | hbase shell

      These snapshots enable point-in-time recovery if you discover issues after migration.

    8. Run meta refresh and refresh hfiles on the read replica:
      echo "refresh_meta" | hbase shell
      hbase org.apache.hadoop.hbase.client.example.RefreshHFilesClient "table_name'"

      Refreshing confirms the read replica has the most current region assignments, table structure, and HFile references before taking over production traffic.

    9. Check for inconsistencies in the read-replica cluster
      Run the HBCK2 tool on the read-replica cluster to identify potential issues:

      sudo -u hbase hbase hbck > hbck_report.txt

      When a read replica is created, both the primary and replica clusters show metadata inconsistencies referencing each other’s meta folders: “There is a hole in the region chain”. The primary cluster complains about meta_<read-replica-cluster-id>, while the read replica complains about the primary’s meta folder. This inconsistency doesn’t impact cluster operations but shows up in hbck reports. For a clean hbck report after switching to the read replica and terminating the primary cluster, manually delete the old primary’s meta folder from Amazon S3 after taking a backup of it.

      Additionally, check the HBase Master UI to visually confirm cluster health. Verifying the read-replica cluster has a clean, consistent state before promotion prevents potential data access issues after cutover.

    Phase 2: Cutover

    Perform the actual migration by shutting down the primary cluster and promoting the read replica. The steps in this phase minimize the window when your cluster is unavailable to applications.

    1. Remove the primary cluster from DNS routing
      Update DNS entries to direct traffic away from the primary cluster, preventing new requests from reaching it during shutdown.
    2. Flush in-memory data to Amazon S3
      Flush in-memory data to confirm durability in Amazon S3:

      # Flush application data  
      echo "flush 'usertable'" | hbase shell
      # Flush system tables
      echo "flush 'hbase:meta'" | hbase shell
      echo "flush 'hbase:namespace'" | hbase shell

      Flushing forces data still in memory (in MemStores, HBase’s write cache) to be written to persistent storage (Amazon S3), preventing data loss during the transition between clusters.

    3. Terminate the primary cluster
      Terminate the primary cluster after confirming the data is persisted to Amazon S3. This step releases resources and eliminates the possibility of split-brain scenarios where both clusters might accept writes to the same dataset.
    4. Promote the read replica to active status
      Convert the read replica to read-write mode:

      echo "readonly_switch false" | hbase shell  
      echo "readonly_state" | hbase shell  # Verify the switch was successful

      The promotion process automatically refreshes meta and HFiles, capturing final changes from the flush operations and confirming complete data visibility.

      When you promote the cluster, it transitions from read-only to read-write mode, allowing it to accept application write operations and fully replace the old cluster’s functionality.

    5. Update DNS to point to the new active cluster
      Update DNS entries to direct traffic to the new active cluster. Routing client traffic to the new cluster restores service availability and completes the migration from the application perspective.

    Phase 3: Validation

    With your new cluster now active, you’re ready to verify that everything is working correctly before declaring the migration complete.

    Execute test write operations to confirm the cluster accepts writes properly. Check the HBase Master UI to verify regions are serving both read and write requests without errors. At this point, your migration to the new Amazon EMR release is complete, and your applications can connect to the new cluster and resume normal read-write operations.

    Key benefits

    The read-replica prewarm approach delivers several important advantages over traditional HBase upgrade methods. Most notably, you can reduce service interruption from hours to minutes by preparing your new cluster in parallel with your running production environment.

    Before committing to the upgrade, you can thoroughly test that data is readable and accessible in the new version. The system loads and assigns regions before activation, eliminating the lengthy startup time that traditionally causes extended downtime. This pre-warming process means your new cluster is ready to serve traffic immediately upon promotion.

    You also gain the ability to validate multiple aspects of your deployment before cutover, including data integrity, read performance, cluster stability, and configuration correctness. This validation happens while your production cluster continues serving traffic, reducing the risk of discovering issues during your maintenance window.

    For testing and validation workflows, you can run parallel testing environment by creating multiple HBase read replicas. However, you should verify that only one HBase cluster remains in read-write mode to the Amazon S3 data store to prevent data corruption and consistency issues.

    Rollback procedures

    Always thoroughly test your HBase rollback procedures before implementing upgrades in production environments.

    When rolling back HBase clusters in Amazon EMR, you have two primary options.

    • Option 1 involves launching a new cluster with the previous HBase version that points to the same Amazon S3 data location as the upgraded cluster. This approach is straightforward to implement, preserves data written before and after the upgrade attempt, and offers faster recovery with no additional storage requirements. However, it risks encountering data compatibility issues if the upgrade modified data formats or metadata structures, potentially leading to unexpected behavior.
    • Option 2 takes a more cautious approach by launching a new cluster with the previous HBase version and restoring from snapshots taken before the upgrade. This method guarantees a return to a known, consistent state, eliminates version compatibility risks, and provides complete isolation from corruption introduced during the upgrade process. The tradeoff is that data written after the snapshot was taken will be lost, and the restoration process requires more time and planning.

    For production environments where data integrity is paramount, the snapshot-based approach (option 2) is generally preferred despite the potential for some data loss.

    Considerations

    • Store file tracking migration: Migrating from Amazon EMR 7.3 (or earlier) requires disabling and dropping the hbase:storefile table on the primary cluster, then flushing metadata. When launching the new read-replica cluster, configure the DefaultStoreFileTracker implementation using the hbase.store.file-tracker.impl property. When operational, run change_sft commands to switch tables to FILE tracking method, providing seamless data file access during migration.
    • Multi-AZ deployments: Consider network latency and Amazon S3 access patterns when deploying read replicas across Availability Zones. Cross-AZ data transfer might impact read latency for the read-replica cluster.
    • Cost impact: Running parallel clusters during migration incurs additional infrastructure costs until the primary cluster is terminated.
    • Disabled tables: The disabled state of tables in the primary cluster is a cluster-specific administrative property that isn’t propagated to the read-replica cluster. If you want them disabled in the read replica, you must explicitly disable them.
    • Amazon EMR 5.x cluster upgrade: Direct upgrade from Amazon EMR 5.x to Amazon EMR 7.x using this feature isn’t supported because of the major HBase version change from 1.x to 2.x. For upgrading from Amazon EMR 5.x to Amazon EMR 7.x, follow the steps in our best practices: AWS EMR Best Practices – HBase Migration

    Conclusion

    In this post, we showed you how the read-replica prewarm feature of Amazon EMR 7.12 improves HBase cluster operations by minimizing the hard cutover constraints that make infrastructure changes challenging. This feature gives you a consistent blue-green deployment pattern that reduces risk and downtime for version upgrades and security patches.

    When you can thoroughly validate changes before committing to them and reduce service interruption from hours to minutes, you can maintain HBase infrastructure more confidently and efficiently. You can now take a more proactive approach to cluster maintenance, security compliance, and performance optimization with greater confidence in your operational processes.

    To learn more about Amazon EMR and HBase on Amazon S3, visit the Amazon EMR documentation. To get started with read replicas, see the HBase on Amazon S3 guide .


    About the authors

    Suthan Phillips

    Suthan Phillips

    Suthan is a Senior Analytics Architect at AWS, where he helps customers design and optimize scalable, high-performance data solutions that drive business insights. He combines architectural guidance on system design and scalability with best practices to provide efficient, secure implementation across data processing and experience layers. Outside of work, Suthan enjoys swimming, hiking, and exploring the Pacific Northwest.

    Ramesh Kandasamy

    Ramesh Kandasamy

    Ramesh is an Engineering Manager at Amazon EMR. He is a long tenured Amazonian dedicated to solve distributed systems problems.

    Mehul Gulati

    Mehul Gulati

    Mehul is a Software Development Engineer for Amazon EMR at Amazon Web Services. His expertise spans big data systems including HBase, Hive, Tez, and distributed storage solutions. His customer obsession and focus on reliability helps Amazon EMR deliver reliable and efficient big data processing capabilities to customers.

    How Tipico democratized data transformations using Amazon Managed Workflows for Apache Airflow and AWS Batch

    Post Syndicated from Jake J. Dalli original https://aws.amazon.com/blogs/big-data/how-tipico-democratized-data-transformations-using-amazon-managed-workflows-for-apache-airflow-and-aws-batch/

    This is a guest post by Jake J. Dalli, Data Platform Team Lead at Tipico, in partnership with AWS.

    Tipico is the number one name in sports betting in Germany. Every day, we connect millions of fans to the thrill of sport, combining technology, passion, and trust to deliver fast, secure, and exciting betting, both online and in more than a thousand retail shops across Germany. We also bring this experience to Austria, where we proudly operate a strong sports betting business.

    In this post, we show how Tipico built a unified data transformation platform using Amazon Managed Workflows for Apache Airflow (Amazon MWAA) and AWS Batch.

    Solution overview

    To support critical needs such as product monitoring, customer insights, and revenue assurance, our central data function needed to provide the tools for several cross-functional analytics and data science teams to run scalable batch workloads on the existing data warehouse, powered by Amazon Redshift. The workloads of Tipico’s data community included extract, transform, and load (ELT), statistical modeling, machine learning (ML) training, and reporting across diverse frameworks and languages.

    In the past, analytics teams operated in isolation, distinct from each other and the central data function. Different teams maintained their own set of tools, often performing the same function and creating data silos. Lack of visibility meant a lack of standardization. This siloed approach slowed down the delivery of insights and prevented the company from achieving a unified data strategy that ensured availability and scalability.

    The need to introduce a single, unified platform that promoted visibility and collaboration became clear. However, the diversity of workloads brought another layer of complexity. Teams needed to tackle different types of problems and brought distinct skillsets and preferences in tooling. Analysts might rely heavily on SQL and business intelligence (BI) platforms, whereas data scientists preferred Python or R, and engineers leaned on containerized workflows or orchestration frameworks.

    Our goal was to architect a new system that supports diversity while maintaining operational control, delivering an open orchestration platform with built-in security isolation, scheduling, retry mechanisms, fine-grained role-based access control (RBAC), and governance features such as two-person approval for production workflows. We achieved this by designing a system with the following principles:

    1. Bring Your Own Container (BYOC) – Teams are given the flexibility to package their workloads as containers and are free to choose dependencies, libraries, or runtime environments. For teams with highly specialized workloads, this meant that they could work in a setup tailored to their needs while also operating within a harmonized platform. On the other hand, teams that didn’t require fully customized environments could redesign their workloads to align with existing workloads.
    2. Centralized orchestration for full transparency – All teams can see all workflows and build interdependencies between them
    3. Shared orchestration, isolated compute – Workloads run in team-specific Docker containers within a unified compute environment, providing scalability while keeping execution traceable to each team.
    4. Standardized interfaces, flexible execution – Common patterns (operators, hooks, logging, or monitoring) reduce complexity, and teams retain freedom to innovate within their containers.
    5. Cross-team approvals for critical workflows stored inside version control – Changes follow a four-eye principle, requiring review and approval from another team before execution, providing accountability and reducing risk. This allowed our core data function to monitor and contribute suggestions to work across different analytics teams.

    We devised a system wherein orchestration and execution of tasks operate on shared infrastructure, which teams interact with through domain-specific infrastructure. In Tipico’s case, each team pushes images to team-owned container instances. Such containers provide code for workflows, including execution of ELT pipelines or transformations on top of domain-specific data lakes.

    The following diagram shows the solution architecture.

    The technical challenge was to architect a flexible and high-performance orchestration layer that could scale reliably while also remaining framework-agnostic, integrating seamlessly with existing infrastructure.

    When designing our system, we were aware of the several container orchestration solutions offered by Amazon Web Services (AWS), including Amazon Elastic Kubernetes Service (Amazon EKS), Amazon Elastic Container Service (Amazon ECS), and AWS Batch, among others. In the end, the team selected AWS Batch because it abstracts away cluster management, provides elastic scaling, and inherently supports batch workloads as a design feature.

    Solution details

    Before adopting the current solution, Tipico experimented with operating a self-managed Apache Airflow setup. Although it was functional, it became increasingly burdensome to maintain. The shift toward a managed and scalable solution was driven by the need to focus more on empowering teams to deliver rather than maintaining the infrastructure. Tipico replatformed the central orchestration solution using Amazon MWAA and AWS Batch.

    Amazon MWAA is a fully managed service that simplifies running open source Apache Airflow on AWS. Users can build and execute data processing workflows while integrating seamlessly with various AWS services, which means developers and data engineers can concentrate on building workflows rather than managing infrastructure.

    AWS Batch is a fully managed service that simplifies batch computing in the cloud so users can run batch jobs without needing to provision, manage, or maintain clusters. It automates resource provisioning and workload distribution, with users only paying for the underlying AWS resources consumed.

    The new design provides a unified framework where analytics workloads are containerized, orchestrated, and executed on scalable compute and integrated with persistent storage:

    1. Containerization – Analytics workloads are packaged into Docker containers, with dependencies bundled to provide reproducibility. These images are versioned and stored in Amazon Elastic Container Registry (Amazon ECR). This approach decouples execution from infrastructure and enables consistent behavior across environments.
    2. Workflow orchestration – Airflow Directed Acyclic Graphs (DAGs) are version-controlled in Git and deployed to Amazon MWAA using a continuous integration and continuous delivery (CI/CD) pipeline. Amazon MWAA schedules and orchestrates tasks, triggering AWS Batch jobs using custom operators. Logs and metrics are streamed to Amazon CloudWatch, enabling real-time observability and alerting.
    3. Data persistence – Workflows interact with Amazon Simple Storage Service (Amazon S3) for durable storage of inputs, outputs, and intermediate artifacts. Amazon Elastic File System (Amazon EFS) is mounted to Amazon MWAA for fast access to shared code and configuration files, synchronized continuously from the Git repository.
    4. Scalable compute – Amazon MWAA triggers AWS Batch jobs using standardized job definitions. These jobs run in elastic compute environments such as Amazon Elastic Compute Cloud (Amazon EC2) or AWS Fargate, with secrets securely injected using AWS Secrets Manager. AWS Batch environments auto scale based on workload demand, optimizing cost and performance.
    5. Security and governance – AWS Identity and Access Management (IAM) roles are scoped per team and workload, providing least-privilege access. Job executions are logged and auditable, with fine-grained access control enforced across Amazon S3, Amazon ECR, and AWS Batch.

    Common operators

    To streamline the execution of batch jobs across teams, we developed a shared operator that wraps the built-in Airflow AWS Batch operator. This abstraction simplifies the execution of containerized workloads by encapsulating common logic such as:

    1. Job definition selection
    2. Job queue targeting
    3. Environment variable injection
    4. Secrets resolution
    5. Retry policies and logging configuration

    Parameterization is handled using Airflow Variables and XComs, enabling dynamic behavior across DAG runs. The operator is maintained in a shared Git repository, versioned and centrally governed, but accessible to all teams.

    To further accelerate development, some teams use a DAG Factory pattern, which programmatically generates DAGs from configuration files. This reduces boilerplate and enforces consistency so teams can define new workflows declaratively.

    By standardizing this operator and supporting patterns, Tipico reduces onboarding friction, promotes reuse, and provides consistent observability and error handling across the analytics ecosystem.

    Governance

    Governance is enforced through a combination of fine-grained IAM roles, AWS IAM Identity Center and automated role mapping. Each team is assigned a dedicated IAM role, which governs access to AWS services such as Amazon S3, Amazon ECR, AWS Batch and Secrets Manager. These roles are tightly scoped to minimize the extent of damage and provide traceability.

    Given that the airflow environment runs version 2.9.2, which doesn’t support multi-tenant access, Tipico developed a custom component that dynamically maps AWS IAM roles to Airflow roles. The component, which executes periodically using Airflow itself, dynamically syncs IAM role assignments with Airflow’s internal RBAC model. Airflow tags are used to govern access to different DAGs, governing which teams have access to execute or modify the settings on the DAG. This aligns access permissions remain with organizational structure and team responsibilities.

    Adoption

    The shift toward a managed, scalable solution was driven by the need for greater team autonomy, standardization, and scalability. The journey began with a single analytics team validating the new approach. When it was successful, the platform team generalized the solution and rolled it out incrementally to other teams, refining it with each iteration.One of the biggest challenges was migrating legacy code, which often included outdated logic and undocumented dependencies. To support adoption, Tipico introduced a structured onboarding process with hands-on training, real use cases, and internal champions. In some cases, teams also had to adopt Git for the first time—marking a broader shift toward modern engineering practices within the analytics organization.

    Key benefits

    One of the most valuable outcomes of our new architecture that is primarily built around Amazon MWAA and AWS Batch is to accelerate analytics teams’ time to value. Analysts can now focus on building transformation logic and workloads without worrying about the underlying infrastructure. With this system, analysts can rely on preprepared integrations and analytics patterns used across different teams, supported by standard interfaces developed by the core data team.

    Aside from building analytics on Amazon Redshift, the orchestration solution also interfaces with several other analytics services such as Amazon Athena and AWS Glue ETL, providing maximum flexibility on the type of workloads being delivered. Teams within the organization have also shared practices in using different frameworks, such as dbt Labs, to reuse custom developments to carry out standard processes.

    Another valuable outcome is the ability to clearly segregate costs across teams. Within the architecture, Airflow delegates heavy lifting to AWS Batch, providing task isolation that spans beyond Airflow’s built-in workers. Through this, we gain granular visibility into resource usage and accurate cost attribution, promoting financial accountability across the organization.

    Finally, the platform also provides embedded governance and security, with RBAC and standardized secrets management providing an operationalized model for securing and governing working flows across different teams.

    Teams can now focus on building and iterating quickly, knowing that the surrounding structures provide full transparency and are coherent with the organization’s governance, architecture, and FinOps goals. At the same time, centralized orchestration fosters a collaborative environment where teams can discover, reuse, and build upon each other’s workflows, driving innovation and reducing duplication across the data landscape.

    Conclusion

    By reimagining our orchestration layer with Amazon MWAA and AWS Batch, Tipico has unlocked a new level of agility and transparency across its data workflows.

    Previously, analytics teams faced long lead times, often stretching into weeks, to implement new reporting use cases. Much of this time was spent identifying datasets, aligning transformation logic, discovering integration options, and navigating inconsistent quality assurance processes. Today, that has changed. Analysts can now develop and deploy a use case within a single business day, shifting their focus from groundwork to action.

    The modern architecture empowers teams to move faster and more independently within a secure, governed, and scalable framework. The result is a collaborative data ecosystem where experimentation is encouraged, operational overhead is reduced, and insights are delivered at speed.

    To start building your own orchestrated data platform, explore the Get started with Amazon Managed Workflows for Apache Airflow and AWS Batch User Guide. These services can help you achieve similar results in democratizing data transformations across your organization. For hands-on experience with these solutions, try our Amazon MWAA for Analytics Workshop or contact your AWS account team to learn more.


    About the authors

    Jake J. Dalli

    Jake J. Dalli

    Jake is the Data Platform Team Lead at Tipico, where he is engaged in architecting and scaling data platforms that enable reliable analytics and informed decision-making across the organization. He’s passionate about empowering analysts to deliver faster insights by simplifying complex systems and accelerating time to value.

    David Greenshtein

    David Greenshtein

    David is a Senior Specialist Solutions Architect for Analytics at AWS, with a passion for building distributed data platforms aligned with governance requirements. He works with customers to design and implement scalable, governed analytics solutions to turn data into actionable insights and measurable business outcomes.

    Hugo Mineiro

    Hugo Mineiro

    Hugo is a Senior Analytics Specialist Solutions Architect based in Geneva. He focuses on helping customers across various industries build scalable and high-performing analytics solutions. He loves playing football and spending time with friends.

    Modernize game intelligence with generative AI on Amazon Redshift

    Post Syndicated from Narendra Gupta original https://aws.amazon.com/blogs/big-data/modernize-game-intelligence-with-generative-ai-on-amazon-redshift/

    Game studios generate massive amounts of player and gameplay telemetry, but transforming that data into meaningful insights is often slow, technical, and dependent on SQL expertise. With the new Amazon Redshift integration for Amazon Bedrock Knowledge Bases, teams can unlock instant, AI-powered analytics by asking questions in natural language. Analysts, product managers, and designers can now explore Amazon Redshift data conversationally—no query writing required—and Amazon Bedrock automatically generates optimized SQL, executes it on Amazon Redshift, and returns clear, actionable answers. This brings together the scale and performance of Amazon Redshift with the intelligence of Amazon Bedrock, enabling faster decisions, deeper player understanding, and more engaging game experiences.

    Amazon Redshift can be used as a structured data source for Amazon Bedrock Knowledge Bases, allowing for natural language querying and retrieval of information from Amazon Redshift. Amazon Bedrock Knowledge Bases can transform natural language queries into SQL queries, so users can retrieve data directly from the source without needing to move or preprocess the data. A game analyst can now ask, “How many players completed all the levels in a game?” or “List the top 5 players by the number of times the game was played,” and Amazon Bedrock Knowledge Bases automatically translates that query into SQL, runs the query against Amazon Redshift, and returns the results—or even provides a summarized narrative response.

    To generate accurate SQL queries, Amazon Bedrock Knowledge Bases uses database schema, previous query history, and other domain or business knowledge such as table and column annotations that are provided about the data sources. In this post, we discuss some of the best practices to improve accuracy while interacting with Amazon Bedrock using Amazon Redshift as the knowledge base.

    Solution overview

    In this post, we illustrate the best practices using gaming industry use cases. You will converse with players and their game attempts data in natural language and get the response back in natural language. In the process, you will learn the best practices. To follow along with the use case, follow these high-level steps:

    1. Load game attempts data into the Redshift cluster.
    2. Create a knowledge base in Amazon Bedrock and sync it with the Amazon Redshift data store.
    3. Review the approaches and best practices to improve the accuracy of response from the knowledge base.
    4. Complete the detailed walkthrough for defining and using curated queries to improve the accuracy of responses from the knowledge base.

    Prerequisites

    To implement the solution, you need to complete the following prerequisites:

    Load game attempts and players data

    To load the datasets to Amazon Redshift, complete the following steps:

    1. Open Amazon Redshift Query Editor V2 or another SQL editor of your choice and connect to the Redshift database.
    2. Run the following SQL to create the data tables to store games attempts and player details:
      CREATE TABLE game_attempts (
          player_id numeric(10, 0), -- Player ID.
          level_id numeric(5, 0), -- Game level ID
          f_success integer, -- Indicates whether user completed the level (1: completed, 0: fails).
          f_duration real, -- duration of the attempt.  Units in seconds
          f_reststep real, -- The ratio of the remaining steps to the limited steps.  Failure is 0.
          f_help integer, -- Whether extra help, such as props and hints, was used.  1- used, 0- not used
          game_time timestamp, -- Attempt timestamp
          bp_used boolean -- Whether bonus packages used or not.  true: used, false: not used.
      );
      CREATE TABLE players (
      	player_id numeric(10, 0), -- Player ID
      	lost_label boolean, -- Indicated if user retained or lost.  true: lost ,  false: retained
      	bp_category integer -- bonus package category codes
      );

    3. Download the game attempts and players datasets to your local storage.
    4. Create an Amazon Simple Storage Service (Amazon S3) bucket with a unique name. For instructions, refer to Creating a general purpose bucket.
    5. Upload the downloaded files into your newly created S3 bucket.
    6. Using the following COPY command statements, load the datasets from Amazon S3 into the new tables you created in Amazon Redshift. Replace <<your_s3_bucket>> with the name of your S3 bucket and <<your_region>> with your AWS Region:
      COPY game_attempts 
      FROM 's3://<<your_s3_bucket>>/game_attempts.csv' 
      IAM_ROLE DEFAULT 
      FORMAT AS CSV 
      IGNOREHEADER 1;
      COPY players
      FROM 's3://<<your_s3_bucket>>/players.csv' 
      IAM_ROLE DEFAULT 
      FORMAT AS CSV 
      IGNOREHEADER 1;

    Create knowledge base and sync

    To create a knowledge base and sync your data store with your knowledge base, complete these steps:

    1. Follow the steps at Create a knowledge base by connecting to a structured data store.
    2. Follow the steps at Sync your structured data store with your Amazon Bedrock knowledge base.

    Alternatively, you can refer Step 4: Set up Bedrock Knowledge Bases in Accelerating Genomic Data Discovery with AI-Powered Natural Language Queries in the AWS for Industries blog.

    Approaches to improve the accuracy

    If you’re not getting the expected response from the knowledge base, you can consider these key strategies:

    1. Provide additional information in the Query Generation Configuration. The knowledge base’s response accuracy can be improved by providing supplementary information and context to help it better understand your specific use case.
    2. Use representative sample queries. Running example queries that reflect common use cases helps train the knowledge base on your database’s specific patterns and conventions.

    Consider a database that stores player information using country codes rather than full country names. By running sample queries that demonstrate the relationship between country names and their corresponding codes (for example, “USA” for “United States”), you help the knowledge base understand how to properly translate user requests that reference full country names into queries using the correct country codes. This approach helps connect natural language requests and your database’s specific implementation details, resulting in more accurate query generation.

    Before we dive into more optimizations options, let’s explore how you can personalize the query engine to generate queries for a specific query engine. In this walkthrough, we use Amazon Redshift. Amazon Bedrock Knowledge Bases analyzes three key components to generate accurate SQL queries:

    • Database metadata
    • Query configurations
    • Historical query and conversation data

    The following graphic illustrates this flow.

    Amazon Bedrock Knowledge Bases architecture diagram showing structured data retrieval workflow with generative AI

    You can configure these settings to enhance query accuracy in two ways:

    • When creating a new Amazon Redshift knowledge base
    • By editing the query engine settings of an existing knowledge base

    To configure setting when creating new knowledge base, follow steps on Create a knowledge base by connecting to a structured data store and configure below parameters in (Optional) Query configurations section as shown in following screenshot:

    1. Table and column descriptions
    2. Table and column inclusions/exclusions
    3. Curated queries

    Amazon Bedrock Knowledge Base creation interface showing Redshift database configuration options

    To configure setting when editing the query engine of an existing knowledge base, follow these steps:

    1. On the Amazon Bedrock console in the left navigation pane, choose Knowledge Bases and select your Redshift Knowledge Base.
    2. Choose your query engine and choose Edit,
    3. Configure below parameters in (Optional) Query configurations section as shown in following screenshot:
      1. Table and column descriptions
      2. Table and column inclusions/exclusions
      3. Curated queries

    Edit query engine configuration page for Amazon Bedrock Knowledge Base with Redshift settings

    Let’s explore the available query configuration options in more detail to understand how these help the knowledge base generate a more accurate response.

    Table and column descriptions provide essential metadata that helps Amazon Bedrock Knowledge Bases understand your data structure and generate more accurate SQL queries. These descriptions can include table and column purposes, usage guidelines, business context, and data relationships.

    Follow these best practices for descriptions:

    • Use clear, specific names instead of abstract identifiers
    • Include business context for technical fields
    • Define relationships between related columns

    For example, consider a gaming table with timestamp columns named t1, t2, and t3. Adding these descriptions helps the knowledge base generate appropriate queries. For example, if t1 is play start time, t2 is play end time, and t3 is record creation time, adding these descriptions will indicate to the knowledge base to use t2–t1 for finding the game duration.

    Curated queries are a set of predefined question and answer examples. Questions are written as natural language queries (NLQs) and answers are the corresponding SQL query. These examples help the SQL generation process by providing examples of the kinds of queries that should be generated. They serve as reference points to improve the accuracy and relevance of generative SQL outputs. Using this option, you can provide some example queries to the knowledge base for it understand custom vocabulary also. For example, if the country field in the table is populated with a country code, adding an example query will help the knowledge base to convert the country name to a country code before running the query to answer questions on the data of players in a specific country. You can also provide some example complex queries to help the knowledge base to respond to more complex questions. The following is an example query that can be added to the knowledge base:

    Select count(*) from players_address where country = ‘USA’;
    

    With table and column inclusion and exclusion, you can specify a set of tables or columns to be included or excluded for SQL generation. This field is crucial if you want to limit the scope of SQL queries to a defined subset of available tables or columns. This option can help optimize the generation process by reducing unnecessary table or column references. You can also use this option to:

    • Exclude redundant tables, for example, those generated by copying the original table to run a complex analysis
    • Exclude tables and columns containing sensitive data

    If you specify inclusions, all other tables and columns are ignored. If you specify exclusions, the tables and columns you specify are ignored.

    Walkthrough for defining and using curated queries to improve accuracy

    To define and use curated queries to improve accuracy, complete the following steps.

    1. On the AWS Management Console, navigate to Amazon Bedrock and in the left navigation pane, choose Knowledge Bases. Select the knowledge base you created with Amazon Redshift.
    2. Choose Test Knowledge Base, as shown in the following screenshot, to validate the accuracy of the knowledge base response.
      Amazon Bedrock Knowledge Base overview page showing game-rs-kb configuration and status details
    3. On the Test Knowledge Base screen under Retrieval and response generation, choose Retrieval and response generation: data sources and model.
    4. Choose Select model to pick a large language model (LLM) to convert the SQL query response from the knowledge base to a natural language response.
    5. Choose Nova Pro in the popup and choose Apply, as shown in the following screenshot.
      Model selection dialog showing Amazon Nova Pro and other foundation models for Bedrock Knowledge Base

    Now you have Amazon Nova Pro connected to your knowledge base to respond to your queries based on the data available in Amazon Redshift. You can ask some questions and verify them with actual data in Amazon Redshift. Follow these steps:

    1. In the Test section on the right, enter the following prompt, then choose the send message icon, as shown in the following screenshot.
      What is the latest attempt status for player 12004?

      Amazon Bedrock Knowledge Base test interface with configuration panel and preview section

    2. Amazon Nova Pro generates a response using the data stored in the Redshift knowledge base.
    3. Choose Details to see the SQL query generated and used by Amazon Nova Pro, as shown in the following screenshot.
      Test results showing AI-generated response with source details for player attempt status query
    4. Copy the query and enter it in query editor v2 of the Redshift knowledge base, as shown in the following screenshot.
      AWS Redshift Query Editor showing SQL query execution with player game attempt results
    5. Verify that the response generated by Amazon Nova Pro in natural language matches the data in Amazon Redshift and that the generated SQL query is also accurate.

    You can try some more questions to verify the Amazon Nova Pro response, for example:

    What is the lost status for player ID 12004?
    How many levels did the player 12004 play?
    What level did player 12004 play the most?
    Show me the summary of all 14 attempts by player 12004 for level 76.

    But what if the response generated by the knowledge base isn’t accurate? In those cases, you can add additional context the knowledge base can use to provide more accurate responses. For example, try asking the following question:

    How many total players are there?

    In this case, the response generated by the knowledge base doesn’t match the actual player count in Amazon Redshift. The knowledge base reported about 13,589 players and generated the following query to get the player count:

    SELECT COUNT(DISTINCT player_id) AS "Number of Players" FROM games.game_attempts;

    The following screenshot shows this question and result.

    Test preview showing AI response to player count query with citation

    The knowledge base should have used the players table in Amazon Redshift to find the unique players. The correct response is 10,816 players.

    AWS Redshift Query Editor showing COUNT query result of 10,816 players

    To help the knowledge base, add a curated query for it to use the players table instead of the attempts table to find the total player count. Follow these steps:

    1. On the Amazon Bedrock console in the left navigation pane, choose Knowledge Bases and select your Redshift Knowledge Base.
    2. Choose your query engine and choose Edit, as shown in the following screenshot.
      Amazon Bedrock Query Engine configuration page showing Redshift serverless connection details
    3. Expand the Curated queries section and enter the following:
    4. In the Questions field, enter How many total players are there?.
    5. In the Equivalent SQL query field, enter SELECT count(*) FROM “dev”,“games”,“players”;.
    6. Choose Submit, as shown in the following screenshot.
      Edit query engine page showing curated query example for player count
    7. Navigate back to your knowledge base and query engine. Choose Sync to sync the knowledge base. This starts the metadata ingestion process so that data can be retrieved. The metadata allows Amazon Bedrock Knowledge Bases to translate user prompts into a query for the connected database. Refer to Sync your structured data store with your Amazon Bedrock knowledge base for more details.
    8. Return to Test Knowledge Base with Amazon Nova Pro and repeat the question about how many total players there are, as shown in the following screenshot. Now, the response generated by the knowledge base matches the data in player table in Amazon Redshift, and the query generated by the knowledge base uses the curated query with the player table instead of the attempts table to determine the player count.
      Test results showing total player count query with SQL source details

    Cleanup

    For the walkthrough section, we used serverless services, and your cost will be based on your usage of these services. If you’re using provisioned Amazon Redshift as a knowledge base, follow these steps to stop incurring charges:

    1. Delete the knowledge base in Amazon Bedrock.
    2. Shut down and delete your Redshift cluster.

    Conclusion

    In this post, we discussed how you can use Amazon Redshift as a knowledge base to provide additional context to your LLM. We identified best practices and explained how you can improve the accuracy of responses from the knowledge base by following these best practices.


    About the authors

    Narendra Gupta

    Narendra Gupta

    Narendra is a Specialist Solutions Architect at AWS, helping customers on their cloud journey with a focus on AWS analytics services. Outside of work, Narendra enjoys learning new technologies, watching movies, and visiting new places.

    Satesh Sonti

    Satesh Sonti

    Satesh is a Principal Analytics Specialist Solutions Architect based out of Atlanta, specializing in building enterprise data platforms, data warehousing, and analytics solutions. He has over 19 years of experience in building data assets and leading complex data platform programs for banking and insurance clients across the globe.

    Streamline your Amazon Redshift maintenance event notifications with Amazon Simple Notification Service

    Post Syndicated from Sushmita Barthakur original https://aws.amazon.com/blogs/big-data/streamline-your-amazon-redshift-maintenance-event-notifications-with-amazon-simple-notification-service/

    In this post, we take you through customization options for managing the schedule of your Amazon Redshift maintenance events, along with Amazon Redshift maintenance tracks for optimizing cluster performance. We also walk you through how to set up Amazon Redshift event notifications using Amazon SNS.

    For provisioned clusters, Amazon Redshift periodically performs maintenance to apply fixes, enhancements, and new features to your cluster. Amazon Redshift assigns a 30-minute maintenance window. To prioritize business continuity and to align with your operational needs, this maintenance window is fully customizable, either programmatically or through the AWS Management Console for Amazon Redshift. For more information, see Managing clusters using the console.

    A robust notification system is available to inform you about maintenance activities on your Amazon Redshift clusters to help you plan effectively and maintain communication with your users about scheduled system updates. Using the Amazon Redshift integration with Amazon Simple Notification Service (Amazon SNS), you can enable notifications of an upcoming maintenance events by creating an Amazon Redshift event notification subscription.

    Customizing your provisioned cluster maintenance events

    Amazon Redshift provides several ways to control how AWS maintains your provisioned clusters. The following are the primary customization options available:

    • Modifying the schedule for upcoming maintenance events: You can control when we deploy updates to your clusters.
    • Deferring upcoming maintenance: You can defer non-mandatory maintenance updates for a defined period of time.
    • Choosing a maintenance track to optimize performance: You can choose whether your cluster runs the most recently released version or the version released prior to the most recently released version.
    • Receiving notifications of upcoming maintenance: You can set up notifications for upcoming maintenance events scheduled for your clusters.

    There is no set maintenance window for Amazon Redshift Serverless. When a new version becomes available for a workgroup’s chosen track, Amazon Redshift Serverless typically applies the update during an idle period as long as there is no pending track update request. If the workgroup doesn’t experience an idle period within 14 days, Redshift Serverless forces the version update.

    Modifying the schedule for upcoming maintenance events

    If a maintenance event is scheduled for a given week, it starts during the assigned 30-minute maintenance window. While Amazon Redshift is performing maintenance, it terminates queries or other operations that are in progress. If there are no maintenance tasks to perform during the scheduled maintenance window, your cluster continues to operate normally until the next scheduled maintenance window.

    You can change the scheduled maintenance window by modifying the cluster, either programmatically or by using the Amazon Redshift console. You can find the maintenance window and set the day and time it occurs for the cluster under the Maintenance tab.

    Deferring upcoming maintenance

    Amazon Redshift provides additional control over cluster maintenance by deferring upcoming maintenance for up to 45 days. This feature is invaluable when you need uninterrupted cluster access during critical business periods. For instance, if your cluster’s maintenance window is set to Thursday from 5:30–6:00 UTC, and you need to have nonstop access to your cluster for the next 2 weeks, you can defer maintenance to a date 2 weeks from now. We don’t perform maintenance on your cluster during a specified deferment.

    While standard maintenance can be deferred, mandatory updates—such as critical security patches, which typically occur at most annually, or hardware updates—must proceed as required. In these cases, Amazon Redshift notifies you through both the console and your Amazon SNS subscription, marking these as pending events, and implements these changes regardless of deferral settings to maintain the security and reliability of your infrastructure.

    While performing deferred maintenance on Amazon Redshift clusters with Amazon Redshift data sharing configured, maintaining version compatibility between producer and consumer clusters is crucial for supporting reliable data sharing. As a best practice, you should keep producer and consumer clusters within two versions of each other to minimize potential compatibility issues. For instance, if a producer cluster is running version P195, consumer clusters should be between P193 and P197. To support effective version management, you can also use notification systems that provide timely alerts about planned cluster patching, enabling proactive version alignment and reducing the risk of potential data sharing disruptions.

    Choosing a maintenance track to optimize cluster performance

    Amazon Redshift offers two maintenance tracks that provide you control over how and when cluster version updates are applied, helping to ensure optimal performance while minimizing business disruption. The Current track automatically applies updates during your scheduled maintenance window, keeping your cluster on the latest version with the newest features and improvements. For organizations requiring additional validation time, the Trailing track delays version updates after release, allowing thorough testing of your workloads in development environments before production deployment.

    Using the Amazon Redshift Trailing track in your production environment, and the Current track in your testing and development environment, gives you additional diligence and time to evaluate the latest release. This approach enables you to validate version updates thoroughly before they reach your production environment. Additionally, scheduling maintenance windows during off-peak hours and establishing a communication protocol to notify stakeholders about upcoming maintenance events minimizes potential impact on production because of maintenance events.

    Receiving notifications of upcoming maintenance events

    By setting up an Amazon SNS email notification, you can receive real-time updates about your cluster’s maintenance details directly in your inbox. See Amazon Redshift provisioned cluster event notifications for maintenance event categories along with event ID, severity, and notification descriptions.

    Set up Amazon Redshift event notifications using Amazon SNS

    This section demonstrates how you can set up Amazon SNS notifications for Amazon Redshift maintenance events. For setting up the event notification, we showcase the following two options in this post:

    Amazon SNS notifications can also be set up using AWS Command Line Interface (AWS CLI).

    Prerequisites

    We assume you have already deployed an Amazon Redshift provisioned cluster. For more information on creating a provisioned cluster, see Creating a cluster.

    You also need AWS Identity and Access Management (IAM) permission to create event subscriptions in an Amazon Redshift cluster and topics in Amazon SNS. For more information, see Setting up access for Amazon SNS.

    Using the console

    In this section, you set up notifications for Amazon Redshift maintenance events from the AWS console.

    1. Open the Amazon Redshift console.
    2. In the left navigation pane, choose Amazon Redshift and then choose Events.
    3. Select Event Subscriptions and then choose Create event subscription.
    4. On the Create event subscription page, enter the following information:
      1. In the Subscription details section, under Event subscription name, enter a name for the event.
      2. In the Subscription type section, under Source type, select Cluster.
      3. For Cluster, choose Select clusters, and then select your cluster IDs.
      4. For Categories, select your categories.
      5. For Severity, select either Error or Info, Error.
      6. In the Subscription actions section, select an existing topic or choose Create a new Amazon SNS topic, enter a topic name and then choose Create topic. See create a topic for information about creating a new topic using the Amazon SNS console.
      7. Choose Create event subscription.


    5. Under the Event subscriptions section, you can now see the new event subscription.
    6. In the Amazon SNS console, choose Topics and select the topic you configured in Amazon Redshift events in the previous step.
    7. Choose Create Subscription, under Protocol choose Email and enter a valid email address and choose Create Subscription. You can also select additional protocols based on your preference.
    8. Choose Pending Subscription and choose Request Confirmation. After the confirmation email is received, choose the Confirm Subscription link in the email.

    These event notifications work at the AWS account level.

    Using an AWS CloudFormation stack

    In this section, you build and configure event notifications on existing Amazon Redshift clusters using an AWS CloudFormation stack:

    1. Download this CloudFormation template.
    2. Go to the AWS CloudFormation console.
    3. Choose Create Stack and select With new resources (standard).
    4. Under Specify template, select Upload a template file.
    5. Select Choose file and upload the CloudFormation template you downloaded in Step 1 and choose Next.
    6. In Stack Name, enter AmazonRedshift-EventSubscription.
    7. Enter the Parameters as follows:
      1. For ClusterIdentifier, enter the value for your Amazon Redshift cluster. This can be found by navigating to the Amazon Redshift console and locating the cluster identifier. To subscribe for all clusters in your account, leave this field blank.
      2. For EmailAddress, enter a valid email address.
      3. For EventSubscriptionName, enter the value for your event subscription. (for example, Redshift-event-subscription).
      4. For MonitorAllClusters, select from dropdown:
        • Select False if you entered a cluster identifier (subscribing to notification for one cluster)
        • Select True if you want to monitor all clusters.
      5. For Severity Level, select from dropdown:
        • Select Error if you want to subscribe to error notifications only.
        • Select Info if you want to subscribe to both error and information notifications.


    8. Choose Next, review the final page, and choose Submit.
    9. You will receive an email with subject AWS Notification – Subscription Confirmation. Choose Confirm subscription.
    10. Go to the Amazon Redshift console and under Events, verify the event subscription.

    Sample email notifications from Amazon SNS

    In this section, we show you some examples of notification emails sent through Amazon SNS based on the configuration:

    Database Update notification:

    Amazon Redshift regularly releases cluster versions. The Scheduled Database Update notification, shown in the following screenshot, is sent before an upcoming Amazon Redshift patch version upgrade.

    System Update notification:

    AWS performs regular updates to the underlying hardware and operating system of Amazon Redshift clusters, including security patches and performance improvements. The Scheduled System Update notification, shown in the following screenshot, is sent before scheduled hardware and OS updates.

    If you’re running your non-production clusters on the Current track and production services on the Trailing track, you can receive notifications when your non-production clusters undergo patching, so you can proactively test the release before it goes to your production servers. You can promptly report issues with the update through the AWS Support Center console. If the reported issues are still present when your production clusters are scheduled for the same patch in the Trailing track, you can defer maintenance until the concerns are resolved for stability. To learn how to change tracks for an Amazon Redshift cluster, see Switching between tracks.

    Stay informed about version updates using RSS feeds

    To stay informed about the latest cluster versions released for Amazon Redshift, you can also use the RSS feed of the Cluster versions for Amazon Redshift page in your monitoring toolkit. Unlike real-time cluster notifications, this feed serves as your window into documentation updates, giving you early updates into published features and best practices. While it won’t alert you about immediate cluster maintenance or security patches, you’ll be notified whenever Amazon updates their cluster management documentation. By adding this RSS feed to your preferred reader, you’re subscribing to a continuous stream of AWS documentation updates, helping you to maintain a proactive rather than reactive approach to your data warehouse management.

    Setting up an RSS feed for your Amazon Redshift documentation is straightforward and offers multiple options to suit your workflow preferences. The key is to first choose your preferred RSS reader, such as Slack or Microsoft Outlook, or your preferred web-based RSS feed reader. To start receiving notifications about AWS documentation updates, add the RSS feed URL to the reader to start receiving updates. After setup, you will receive notifications whenever the Amazon Redshift cluster management documentation is updated, helping to keep you informed about new features and best practices.

    You can also see the updates directly on the Cluster versions for Amazon Redshift page to stay informed whenever a new version has been released and before it’s scheduled to be released to your cluster.

    Cleanup

    If you don’t need the Amazon SNS notification created for this post, delete the Amazon SNS topics from the Amazon SNS console to avoid incurring future charges. If you have configured the notification using AWS CloudFormation, delete the stack to delete related configurations. See Amazon SNS Pricing for pricing information for the service.

    Conclusion

    In this post, you learned how to configure maintenance event notifications for Amazon Redshift provisioned clusters using Amazon SNS. We also explained the details of Amazon Redshift maintenance activities, including how to manage the schedule for upcoming maintenance by using Amazon Redshift maintenance tracks to optimize cluster performance, and using RSS feeds to receive real-time updates about critical cluster information.Upgrading your Amazon Redshift clusters to the suggested maintenance track is critical for optimizing cluster performance and to help to ensure that the latest fixes, security patches and enhancements are applied to your clusters. Seamless integration with the Amazon SNS notification system helps ensure that you’re informed of maintenance events ahead of time, so that you can prepare for them. This proactive approach helps you to plan effectively and maintain communication with your users about scheduled system updates.

    To learn more about Amazon Redshift cluster versions and maintenance windows, see to Cluster versions for Amazon Redshift, Cluster maintenance, and MaintenanceTrack.


    About the authors

    Sushmita Barthakur

    Sushmita Barthakur

    Sushmita is a Senior Data Solutions Architect at AWS, supporting Strategic customers architect their data workloads on AWS. With a background in data analytics, she has extensive experience helping customers architect and build enterprise data lakes, ETL workloads, data warehouses and data analytics solutions, both on-premises and the cloud. Sushmita is based in Florida and enjoys traveling, reading and playing tennis.

    Nidhi Nayak

    Nidhi Nayak

    Nidhi is a Senior Technical Account Manager with AWS, she helps enterprise customers build scalable, high-performance cloud applications and optimize cloud operations. With over a decade of experience in Data Analytics, Nidhi currently focuses on Redshift & Generative AI integration with Redshift.

    Rajesh Pentapati

    Rajesh Pentapati

    Rajesh is a Solutions Architect at AWS. He has expertise in designing and implementing sophisticated enterprise data platforms, comprehensive data warehousing strategies, and innovative analytics solutions, with a emphasis on leveraging Amazon Redshift’s powerful capabilities. Beyond his professional accomplishments, finds joy in playing sports and cherishing quality moments with his family and friends.

    Top 10 best practices for Amazon EMR Serverless

    Post Syndicated from Karthik Prabhakar original https://aws.amazon.com/blogs/big-data/top-10-best-practices-for-amazon-emr-serverless/

    Amazon EMR Serverless is a deployment option for Amazon EMR that you can use to run open source big data analytics frameworks such as Apache Spark and Apache Hive without having to configure, manage, or scale clusters and servers. EMR Serverless integrates with Amazon Web Services (AWS) services across data storage, streaming, orchestration, monitoring, and governance to provide a comprehensive serverless analytics solution.

    In this post, we share the top 10 best practices for optimizing your EMR Serverless workloads for performance, cost, and scalability. Whether you’re getting started with EMR Serverless or looking to fine-tune existing production workloads, these recommendations will help you build efficient, cost-effective data processing pipelines. The following diagram illustrates an end-to-end EMR Serverless architecture, showing how it integrates into your analytics pipelines.

    1. Define applications one time, reuse multiple times

    EMR Serverless applications function as cluster templates that instantiate when jobs are submitted and can process multiple jobs without being recreated. This design significantly reduces startup latency for recurring workloads and simplifies operational management.

    Typical workflow for EMR on EC2 transient cluster:

    Typical workflow for EMR Serverless:

    Applications feature a self-managing lifecycle that provisions resources to be available when needed without manual intervention. They automatically provision capacity when a job is submitted. For applications without pre-initialized capacity, resources are released immediately after job completion. For applications with pre-initialized capacity configured, those pre-initialized workers will stop after exceeding the configured idle timeout (15 minutes by default). You can adjust this timeout at the application level using AutoStopConfig configuration in the CreateApplication or UpdateApplication API. For example, if your jobs run every 30 minutes, increasing the idle timeout can eliminate startup delays between executions.

    Most workloads are suited for on-demand capacity provisioning, which automatically scales resources based on your job requirements without incurring charges when idle. This approach is cost-effective and suitable for typical use cases including extract, transform, and load (ETL) workloads, batch processing jobs, and scenarios requiring maximum job resiliency.

    For specific workloads with strict instant-start requirements, you can optionally configure pre-initialized capacity. Pre-initialized capacity creates a warm pool of drivers and executors that are ready to run jobs within seconds. However, this performance advantage comes with a tradeoff of added cost because pre-initialized workers incur continuous charges even when idle until the application reaches the Stopped state. Additionally, pre-initialized capacity restricts jobs to a single Availability Zone, which reduces resiliency.

    Pre-initialized capacity should only be considered for:

    • Time-sensitive jobs with sub second service level agreement (SLA) requirements where startup latency is unacceptable
    • Interactive analytics where user experience depends on instant response
    • High-frequency production pipelines running every few minutes

    In most other cases, on-demand capacity provides the best balance of cost, performance, and resiliency.

    Beyond optimizing your applications’ use of resources, consider how you organize them across your workloads. For production workloads, use separate applications for different business domains or data sensitivity levels. This isolation improves governance and prevents resource contention between critical and noncritical jobs.

    2. Choose AWS Graviton Processors for better price performance

    Selecting the right underlying processor architecture can significantly impact both performance and cost. Graviton ARM-based processors offer significant performance improvement compared to x86_64.

    EMR Serverless automatically updates to the latest instance generations as they become available, which means your applications benefit from the newest hardware improvements without requiring additional configuration.

    To use Graviton with EMR Serverless, specify ARM64 with the architecture parameter during application creation using the CreateApplication or with the UpdateApplication API for existing applications:

    aws emr-serverless create-application \
      --name my-spark-app \
      -- SPARK \
      --architecture ARM64 \
      --release-label emr-7.12.0

    Considerations when using Graviton:

    • Resource availability – For large-scale workloads, consider engaging with your AWS account team to discuss capacity planning for Graviton workers.
    • Compatibility – Although many commonly used and standard libraries are compatible with Graviton (arm64) architecture, you will need to validate that third-party packages and libraries used are compatible.
    • Migration planning – Take a strategic approach to Graviton adoption. Build new applications on ARM64 architecture by default and migrate existing workloads through a phased transition plan that minimizes disruption. This structured approach will help optimize cost and performance without compromising reliability.
    • Perform benchmarks – It’s important to note that exact price performance will vary by workload. We recommend performing your own benchmarks to gauge specific results for your workload. For more details, refer to Achieve up to 27% better price-performance for Spark workloads with AWS Graviton2 on Amazon EMR Serverless.

    3. Use defaults, right-size workers if needed

    Workers are used to execute the tasks for your workload. While EMR Serverless defaults are optimized out of the box for a majority of use cases, you may need to right-size your workers to improve processing time and optimize cost efficiency. When submitting EMR Serverless jobs, it’s recommended to define Spark properties to configure workers, including memory size (in GB) and number of cores.

    EMR Serverless configures the default worker size of 4 vCPUs, 16 GB memory, and 20 GB disk. Although this generally provides a balanced configuration for most jobs, you might want to adjust the size based on your performance requirements. Even when configuring pre-initialized workers with specific sizing, always set your Spark properties at job submission. This allows your job to use the specified worker sizing rather than default properties when it scales beyond pre-initialized capacity. When right-sizing your Spark workload, it’s important to identify the vCPU:memory ratio for your job. This ratio determines how much memory you allocate per virtual CPU core in your executors. Spark executors need both CPU and memory to process data effectively, and the optimal ratio varies based on your workload characteristics.

    To get started, use the following guidance, then refine your configuration based on your specific workload requirements.

    Executor configuration

    The following table provides recommended executor configurations based on common workload patterns:

    Workload type Ratio CPU Memory Configuration
    Compute intensive 1:2 16 vCPU 32 GB spark.emr-serverless.executor.cores=16spark.emr-serverless.executor.memory=32G
    General purpose 1:4 16 vCPU 64 GB spark.emr-serverless.executor.cores=16spark.emr-serverless.executor.memory=64G
    Memory intensive 1:8 16 vCPU 108 GB spark.emr-serverless.executor.cores=16spark.emr-serverless.executor.memory=108G

    Driver configuration

    The following table provides recommended driver configurations based on common workload patterns:

    Workload type Ratio CPU Memory Configuration
    General purpose 1:4 4 vCPU 16 GB spark.emr-serverless.driver.cores=4spark.emr-serverless.driver.memory=16G
    Apache Iceberg workloads 1:8(Large driver for metadata lookups) 8 vCPU 60 GB spark.emr-serverless.driver.cores=8spark.emr-serverless.driver.memory=60G

    To further monitor and tune your configuration, monitor your workload’s resource consumption using Amazon CloudWatch job worker-level metrics to identify constraints. Track CPU utilization, memory usage, and disk utilization metrics, then use the following table to fine-tune your configuration based on observed bottlenecks.

    Metrics observed Workload type Suggested action
    1 High memory (>90%), Low CPU (<50%) Memory-bound workload Increase vCPU:memory ratio
    2 High CPU (>85%), low memory (<60%) CPU-bound workload Increase vCPU count, maintain 1:4 ratio (For example, if using 8 vCPU, use 32 GB memory)
    3 High storage I/O, normal CPU or memory with long shuffle operations Shuffle-intensive Enable serverless storage or shuffle-optimized disks
    4 Low utilization across metrics Over-provisioned Reduce worker size or count
    5 Consistent high utilization (>90%) Under-provisioned Scale up worker specifications
    6 Frequent GC pauses** Memory pressure Increase memory overhead (10 –15%)

    **You can identify frequent garbage collect (GC) pauses using the Spark UI under the Executors tab. There will be a GC time column that should generally be less than 10% of task time. Alternatively, the driver logs might frequently contain GC (Allocation Failure)] messages.

    4. Control scaling boundary with T-shirt sizing

    By default, EMR Serverless uses dynamic resource allocation (DRA), which automatically scales resources based on workload demand. EMR Serverless continuously evaluates metrics from the job to optimize for cost and speed, removing the need for you to estimate the exact number of workers required.

    For cost optimization and predictable performance, you can configure an upper scaling boundary using one of the following approaches:

    1. Setting the spark.dynamicAllocation.maxExecutors parameter at the job level
    2. Setting the application-level maximum capacity

    Rather than trying to fine-tune spark.dynamicAllocation.maxExecutors to an arbitrary value for each job, you can think about setting this configuration as t-shirt sizes that represent different workload profiles:

    Workload size Use cases spark.dynamicAllocation.maxExecutors
    Small Exploratory queries, development 50
    Medium Regular ETL jobs, reports 200
    Large Complex transformations, large-scale processing 500

    This t-shirt sizing approach simplifies capacity planning and helps you balance performance with cost efficiency based on your workload category, rather than attempting to optimize each individual job.

    For EMR Serverless releases 6.10 and above, the default value for spark.dynamicAllocation.maxExecutors is infinity, but for earlier releases, it’s 100.

    EMR Serverless automatically scales workers up or down based on the workload and parallelism required at every stage of the job. This automatic scaling is continuously evaluating metrics from the job to optimize for cost and speed, which removes the need for you to estimate the number of workers that the application needs to run your workloads.

    However, in some cases, if you have a predictable workload, you might want to statically set the number of executors. To do so, you can disable DRA and specify the number of executors manually:

    spark.dynamicAllocation.=false
    spark.executor.instances=10

    5. Provision appropriate storage for EMR Serverless jobs

    Understanding your storage options and sizing them appropriately can prevent job failures and optimize execution times. EMR Serverless offers multiple storage options to handle intermediate data during job execution. The storage option selected will depend on the EMR release and use case. The storage options available in EMR Serverless are:

    Storage type EMR release Disk size range Use case Benefits
    Serverless Storage (recommended) 7.12+ N/A (auto-scaling) Most Spark workloads, especially data-intensive workloads
    • No storage costs
    • auto-scaling
    • Reduces disk failures
    • Up to 20% cost reduction
    Standard Disks 7.11 and lower 20–200 GB per worker Small to medium workloads processing datasets under 10 TB
    • Simple configuration
    • 20 GB default suitable for most workloads,
    • 200 GB max for optimal throughput
    Shuffle-Optimized Disks 7.1.0+ 20–2,000 GB per worker Large-scale ETL workloads processing multi-TB
    • High IOPS and throughput
    • Up to 2 TB capacity per worker

    By matching your storage configuration to your workload characteristics, you’ll enable EMR Serverless jobs to run efficiently and reliably at scale.

    6. Multi-AZ out-of-the-box with built-in resiliency

    EMR Serverless applications are multi-AZ from the start when pre-initialized capacity isn’t enabled. This built-in failover capability provides resilience against Availability Zone disruptions without manual intervention. A single job will operate within a single Availability Zone to prevent cross-AZ data transfer costs and subsequent jobs will be intelligently distributed across multiple AZs. If EMR Serverless determines that an AZ is impaired, it will submit new jobs to a healthy AZ, enabling your workloads to continue running despite AZ impairment.

    To fully benefit from EMR Serverless multi-AZ functionality verify the following:

    • Configure a network connection to your VPC with multiple subnets across Availability Zones selected
    • Avoid pre-initialized capacity which restricts applications to a single AZ
    • Make sure there are sufficient IP addresses available in each subnet to support the scaling of workers

    In addition to multi-AZ, with Amazon EMR 7.1 and higher, you can enable job resiliency, which allows your jobs to be automatically retried in case errors are encountered. If there are multiple Availability Zones configured, it will also be retried in a different AZ. You can enable this feature for both batch and streaming jobs, though retry behavior differs between the two.

    Configure job resiliency by specifying a retry policy that defines the maximum number of retry attempts. For batch jobs, the default is no automatic retries (maxAttempts=1). For streaming jobs, EMR Serverless retries indefinitely with built-in thrash prevention that stops retries after five failed attempts within 1 hour. You can configure this threshold between 1–10 attempts. For more information, refer to Job resiliency.

    In the event that you need to cancel your job, you can specify a grace period to allow your jobs to shut down cleanly rather than the default behavior of immediate termination. This can also include custom shutdown hooks if you need to perform custom cleanup actions.

    By combining multi-AZ support, automatic job retries, and graceful shutdown periods, you create a robust foundation for EMR Serverless workloads that can tolerate interruptions and maintain data integrity without manual intervention.

    7. Secure and extend connectivity with VPC integration

    By default, EMR Serverless can access AWS services such as Amazon Simple Storage Service (Amazon S3), AWS Glue, Amazon CloudWatch Logs, AWS Key Management Service (AWS KMS), AWS Security Token Service (AWS STS), Amazon DynamoDB, and AWS Secrets Manager. If you want to connect to data stores within your VPC, such as Amazon Redshift or Amazon Relational Database Service (Amazon RDS), you must configure VPC access for the EMR Serverless application.

    When configuring VPC access for your EMR Serverless application, keep these key considerations in mind to gain optimal performance and cost efficiency:

    • Plan for sufficient IP addresses – Each worker uses one IP address within a subnet. This includes the workers that will be launched when your job is scaling out. If there aren’t enough IP addresses, your job might not be able to scale, which could result in job failure. Verify you have adhered to best practices for subnet planning for optimal performance.
    • Set up Gateway endpoints for Amazon S3 for applications in a private subnets – Running EMR Serverless in a private subnet without VPC endpoints for Amazon S3 will route your Amazon S3 traffic through NAT gateways, resulting in additional data transfer charges. VPC endpoints for S3 will keep this traffic within your VPC, reducing costs and improving performance for Amazon S3 operations.
    • Manage AWS Config costs for network interfaces – EMR Serverless generates an elastic network interface record in AWS Config for each worker, which can accumulate costs as your workloads scale. If you don’t require AWS Config tracking for EMR Serverless network interfaces, consider using resource-based exclusions or tagging strategies to filter them out while maintaining AWS Config coverage for other resources.

    For more details, refer Configuring VPC access for EMR Serverless applications.

    8. Simplify job submission and dependency management

    EMR Serverless supports flexible job submission through the StartJobRun API, which accepts the full spark-submit syntax. For runtime environment configuration, use the spark.emr-serverless.driverEnv and spark.executorEnv prefixes to set environment variables for driver and executor processes. This is particularly useful for passing sensitive configuration or runtime-specific settings.

    For Python applications, package dependencies using virtual environments by creating a venv, packaging it as a tar.gz archive, or uploading to Amazon S3 using spark.archives with the appropriate PYSPARK_PYTHON environment variable. This allows Python dependencies to be available across driver and executor workers.

    For improved control under high load, enable job concurrency and queuing (available in EMR 7.0.0+) to limit the number of jobs that can be executed concurrently. With this feature, jobs submitted that exceed the concurrency limit are queued until resources become available.

    You can configure Job concurrency and queue settings using the SchedulerConfiguration property using the CreateApplication or UpdateApplication API.

    --scheduler-configuration '{"maxConcurrentRuns": 5, "queueTimeoutMinutes": 30}'

    9. Use EMR Serverless configurations to enforce limits

    EMR Serverless automatically scales resources based on workload demand, providing optimized defaults that work well for most use cases without requiring Spark configuration tuning. To manage costs effectively, you can configure resource limits that align with your budget and performance requirements. For advanced use cases, EMR Serverless also provides configuration options so you can fine-tune resource consumption and achieve the same efficiency as cluster-based deployments. Understanding these limits helps you balance performance with cost efficiency for your jobs.

    Limit type Purpose How to configure
    Job-level Control resources for individual jobs spark.dynamicAllocation.maxExecutors or spark.executor.instances
    Application-level Limit resources per application or business domain Set maximum capacity when creating the application or while updating.
    Account-level Prevent abnormal resource spikes across all applications Auto-adjustable service quota Max concurrent vCPUs per account; request increases via Service Quotas console

    These three layers of limits work together to provide flexible resource management at different scopes. For most use cases, configuring job-level limits using the t-shirt sizing approach is sufficient, while application and account-level limits provide additional guardrails for cost control.

    10. Monitor with CloudWatch, Prometheus, and Grafana

    Monitoring EMR Serverless workloads simplifies the process of debugging, performing cost optimization, and performance tracking. EMR Serverless offers three tiers of monitoring that work together: Amazon CloudWatch, Amazon Managed Service for Prometheus, and Amazon Managed Grafana.

    1. Amazon CloudWatch – CloudWatch integration is enabled by default and publishes metrics to the AWS/EMRServerless namespace. EMR Serverless sends metrics to CloudWatch every minute at the application level, as well as job, worker-type, and capacity-allocation-type levels. Using CloudWatch, you can configure dashboards for enhanced observability into workloads or configure alarms to alert for job failures, scaling anomalies, and SLA breaches. Using CloudWatch with EMR Serverless provides insights to your workloads so you can catch issues before they impact users.
    2. Amazon Managed Service for Prometheus – With EMR Serverless release 7.1+, you can enable Prometheus for detailed Spark engine metrics to push metrics to Amazon Managed Service for Prometheus. This unlocks executor-level visibility, including memory usage, shuffle volumes, and GC pressure. You can use this to identify memory-constrained executors, detect shuffle-heavy stages, and find data skew.
    3. Amazon Managed Grafana – Grafana connects to both CloudWatch and Prometheus data sources, providing a single pane of glass for unified observability and correlation analysis. This layered approach helps you correlate infrastructure issues with application-level performance problems.

    Key metrics to track:

    • Job completion times and success rates
    • Worker utilization and scaling events
    • Shuffle read/write volumes
    • Memory usage patterns

    For more details, refer to Monitor Amazon EMR Serverless workers in near real time using Amazon CloudWatch.

    Conclusion

    In this post, we shared 10 best practices to help you maximize the value of Amazon EMR Serverless by optimizing performance, controlling costs, and maintaining reliable operations at scale. By focusing on application design, right-sized workloads, and architectural choices, you can build data processing pipelines that are both efficient and resilient.

    To learn more, refer to the Getting started with EMR Serverless guide.


    About the Authors

    Karthik Prabhakar

    Karthik Prabhakar

    Karthik is a Data Processing Engines Architect for Amazon EMR at Amazon Web Services (AWS). He specializes in distributed systems architecture and query optimization, working with customers to solve complex performance challenges in large-scale data processing workloads. His focus spans engine internals, cost-optimization strategies, and architectural patterns that enable customers to run petabyte-scale analytics efficiently.

    Neil Mukerje

    Neil Mukerje

    Neil is a Principal Product Manager at Amazon Web Services.

    Amber Runnels

    Amber Runnels

    Amber is a Senior Analytics Specialist Solutions Architect at Amazon Web Services (AWS) specializing in big data and distributed systems. She helps customers optimize workloads within AWS data offerings to achieve a scalable, high-performing, and cost-effective architecture. Aside from technology, she’s passionate about exploring the many places and cultures this world has to offer, reading novels, and building terrariums.

    Parul Saxena

    Parul Saxena

    Parul is a Senior Big Data Specialist Solutions Architect at Amazon Web Services (AWS). She helps customers and partners build highly optimized, scalable, and secure solutions. She specializes in Amazon EMR, Amazon Athena, and AWS Lake Formation, providing architectural guidance for complex big data workloads and assisting organizations in modernizing their architectures and migrating analytics workloads to AWS.