Tag Archives: Best practices

Simplifying Code Documentation with Amazon Q Developer

Post Syndicated from Jehu Gray original https://aws.amazon.com/blogs/devops/simplifying-code-documentation-with-amazon-q-developer/

In the fast-paced world of software development, maintaining comprehensive documentation often falls to the bottom of priority lists in favor of delivering functionality. Amazon Q Developer’s /doc agent changes this equation by automating README generation and updates. With this tool, the variable of time spent producing documentation is reduced to the point that it’s no longer a burden to the detriment of functionality.

Understanding Amazon Q Developer’s Documentation Generation

The /doc agent leverages generative AI to analyze your codebase and generate comprehensive documentation. Additionally, the agent respects your .gitignore file and excludes files you don’t want to be included in documentation review.

Solution Overview:
As an example, imagine a cloud infrastructure team at a technology consultancy had been working for weeks on their AWS DataSync project. The solution they built provided an elegant CDK implementation that automated data transfer between Amazon S3 buckets using AWS DataSync. The lead engineer had just finished implementing the final IAM role configurations when the product manager requested comprehensive documentation for the next day’s client handoff meeting. The team realized this would typically take hours of focused work. Instead, they decided to try Amazon Q Developer /doc agent.

Getting Started with /doc:

To begin using the /doc agent, you’ll need to:

  1. Set up Amazon Q: Follow these steps
  2. Open your IDE with the Amazon Q extension installed
  3. Click the Amazon Q icon to open the chat panel
  4. Enter /doc to start the documentation process
  5. Select your documentation task:
    1. Create a new README
    2. Update an existing README with recent code changes
This image shows the user entering /doc to start the documentation process

Figure 1 – Entering /doc to start the documentation process.

Example: Creating a New README:

For projects without documentation, simply select: Create a README. It will confirm the project you are creating the README for.

This image shows the user selecting the Create a README option

Figure 2 – Select the Create a README option.

Once you verify the folder and select yes, the agent begins creating the README document for the folder.
Here are the steps it works through: scanning the source files, summarizing the source files, and generating the documentation.

This image shows the user verifying the folder and select yes

Figure 3 – Verify the folder and select yes.

When the document is created, you can preview the README file. The agent then presents you with the ability to either accept the changes or request modifications before implementation.

This image shows the preview of the created README file.

Figure 4 – Preview the created README file.

If you choose to accept, the README file is added to your project.

This image shows the user accepting the changes so the README is added to your project folder

Figure 5 – Accept the changes so the README is added to your project folder.


Example: Updating Documentation with Code Changes

When your code evolves, you can keep the documentation synchronized by using /doc. The agent will review your recent code modifications and suggest appropriate documentation updates.

This image shows when the user selects update an existing README

Figure 6 – Select Update an existing README to make changes to a README file.

Then you can describe the changes you want the agent to make to your README file.

This image shows how you can describe changes you’d like the agent to make

Figure 7 – Describe changes to your README files.

For targeted documentation updates, you can provide specific instructions:

This image shows the user verifying the folder

Figure 8 – Verify the folder and select yes.

Once you’ve made the changes, the agent asks you to verify them by selecting yes.

This image shows the user verifying the changes made

Figure 9 – Verify the changes and select yes.

Advanced Documentation Management

Multi-step Documentation Refinement:

This image shows the steps in Documentation Refinement

Figure 10 – Multi-step Documentation Refinement.


Amazon Q Developer /doc agent allows for iterative improvement of your documentation through feedback loops. After generating initial documentation, you can:

  1. Review the generated content for gaps or inaccuracies
  2. Provide specific feedback to refine particular sections
  3. Request additional sections on complex topics
  4. Gradually build comprehensive documentation through multiple iterations

This iterative approach is particularly valuable for complex projects where documentation needs to evolve alongside the codebase.

Documentation for Specific Components

For modular projects, you can create targeted documentation at different levels:

  • Root-level README for project overview
  • Component-level READMEs for specific modules
  • Service-level documentation for microservices
  • API documentation for interfaces

By combining these documentation levels, you can maintain a hierarchical documentation structure that remains manageable and specific.

Handling Documentation Inheritance

This image shows how to handle Documentation Inheritance.

Figure 11 – Handling Documentation Inheritance.

When working with derived or extended codebases:

  1. Generate base documentation for the parent project
  2. Create specialized documentation for extensions
  3. Cross-reference related documentation to maintain consistency
  4. Use the /doc agent to update specific sections when inheritance patterns change

Documentation Syncing Strategy

This image shows Documentation Syncing Strategy

Figure 12 – Documentation Syncing Strategy.

For teams working on rapidly evolving projects:

  1. Establish a documentation update schedule aligned with sprints
  2. Assign documentation reviews as part of code review processes
  3. Use /doc to generate change summaries after significant updates
  4. Implement a verification process to ensure generated documentation accurately reflects code changes

Best Practices for /doc Agent

To improve results from documentation generation with Amazon Q Developer, follow these best practices:

  1. Optimize repository size: Amazon Q Developer supports documentation generation across your codebase, accommodating projects up to the specified size limits. While documentation for larger repositories may require additional processing time and could provide more generalized results, you have the option to request documentation for specific subsets of code or individual files to receive more detailed insights.
  2. Maintain high-quality code: The quality of documentation Amazon Q Developer generates improves significantly when your code is well-commented and organized, has meaningful naming conventions for programming entities, and follows standard coding conventions.
  3. Be specific with change requests: When requesting specific README changes in natural language, choose to update an existing README and select the option to make a specific change. After initial documentation generation, you can request additional modifications by describing exactly what updates you want.
  4. Craft effective change descriptions: When describing desired updates, include:
    1. Specific sections you want to modify
    2. Exact content you want to add or remove
    3. Particular issues that need correcting
    4. How project functionality should be reflected in the README
    5. References to content available in your codebase.
  5. Understand system limitations: Amazon Q Developer doesn’t have access to private or internal platforms and might lack knowledge of third-party tools, specialized software, or custom tooling in your code. Content requiring this knowledge won’t be documented automatically. In these cases, you’ll need to manually edit the README to include information Amazon Q Developer cannot generate.

Documentation Quotas and Limitations

When working with Amazon Q Developer /doc agent, be aware of these important constraints:

  • Document generations per task: There’s a limit to the number of feedback iterations allowed per documentation session. This quota resets each time you start a new documentation task.
  • File filtering: Amazon Q Developer filters out files or folders defined in your .gitignore file. This helps streamline the documentation process by focusing only on relevant code files.

Conclusion

Amazon Q Developer /doc agent transforms the documentation process from a tedious chore to an automated, efficient workflow. By generating and maintaining READMEs based on your actual code, it ensures documentation remains accurate and up-to-date without consuming precious development time.

As part of Amazon Q Developer’s free tier, the /doc agent is readily available to integrate into your development process. Start using it today to improve your project documentation and enhance team collaboration.

About the Authors:

Jehu Gray

Jehu Gray is a Prototyping Architect at Amazon Web Services where he helps customers design solutions that fits their needs. He enjoys exploring what’s possible with IaC.

Abiola Olanrewaju

Abiola Olanrewaju is a Solutions Architect at AWS, specializing in helping Financial services customers implement scalable solutions that drive business outcomes. He has a keen interest in Data Analytics, Security and Generative AI.

Adeogo Olajide

Adeogo is a Solutions Architect at AWS, where he supports GovTech customers and other public sector customers in their cloud transformation journey. He specializes in designing secure, scalable, and compliant architectures that help public sector organizations modernize their digital services. Outside of work, he enjoys playing and watching soccer.

Joyce Muya

Joyce Muya is a Solutions Architect at AWS where she supports Enterprise Engaged customers in the media and entertainment sector. She specializes in Analytics and AI/ML workloads.

Damola Oluyemo

Damola Oluyemo is a Solutions Architect at Amazon Web Services focused on Enterprise customers. He helps customers design cloud solutions while exploring the potential of Infrastructure as Code and generative AI in software development.

Enhance Agentforce data security with Private Connect for Salesforce Data Cloud and Amazon Redshift – Part 3

Post Syndicated from Yogesh Dhimate original https://aws.amazon.com/blogs/big-data/enhance-agentforce-data-security-with-private-connect-for-salesforce-data-cloud-and-amazon-redshift-part-3/

Data protection is a high priority, particularly as organizations face increasing cybersecurity threats. Maintaining the security of customer data is top priority for AWS and Salesforce. With AWS PrivateLink, Salesforce Private Connect eliminates common security risks associated with public endpoints. Salesforce Private Connect now works with Salesforce Data Cloud to keep your customer data secure when using with key services like Agentforce.

In Part 2 of this series, we discussed the architecture and implementation details of cross-Region data sharing between Salesforce Data Cloud and AWS accounts. In this post, we discuss how to create AWS endpoint services to improve data security with Private Connect for Salesforce Data Cloud.

Solution overview

In this example, we configure PrivateLink for an Amazon Redshift instance to enable direct, private connectivity from Salesforce Data Cloud. AWS recommends that organizations use an Amazon Redshift managed VPC endpoint (powered by PrivateLink) to privately access a Redshift cluster or serverless workgroup. For details about best practices, refer to Enable private access to Amazon Redshift from your client applications in another VPC.

However, some organizations might prefer to use PrivateLink managed by themselves—for example, a Redshift managed VPC endpoint is not yet available in Salesforce Data Cloud, and you need to manage your PrivateLink connection. This post focuses on the solution to configure self-managed PrivateLink between Salesforce Data Cloud and Amazon Redshift in your AWS account to establish private connectivity.

The following architecture diagram shows the steps for setting up private connectivity between Salesforce Data Cloud and Amazon Redshift in your AWS account.

To set up private connectivity between Salesforce Data Cloud and Amazon Redshift, we use the following resources:

Prerequisites

To complete the steps in this post, you must already have Amazon Redshift running in a private subnet and have the permissions to manage it.

Create a security group for the Network Load Balancer

The security group acts as a virtual firewall. The only traffic that reaches the instance is the traffic allowed by the security group rules. To enhance the security posture, you only want to allow traffic to Redshift instances. Complete the following steps to create a security group for your Network Load Balancer (NLB):

  1. On the Amazon VPC console, choose Security groups in the navigation pane.
  2. Choose Create security group.
  3. Enter a name and description for the security group.
  4. For VPC, use the same virtual private cloud (VPC) as your Redshift cluster.
  5. For Inbound rules, add a rule to allow traffic to ingress the listening port 5439 on the load balancer.

  1. For Outbound rules, add a rule to allow traffic to your Redshift instance.

  1. Choose Create security group.

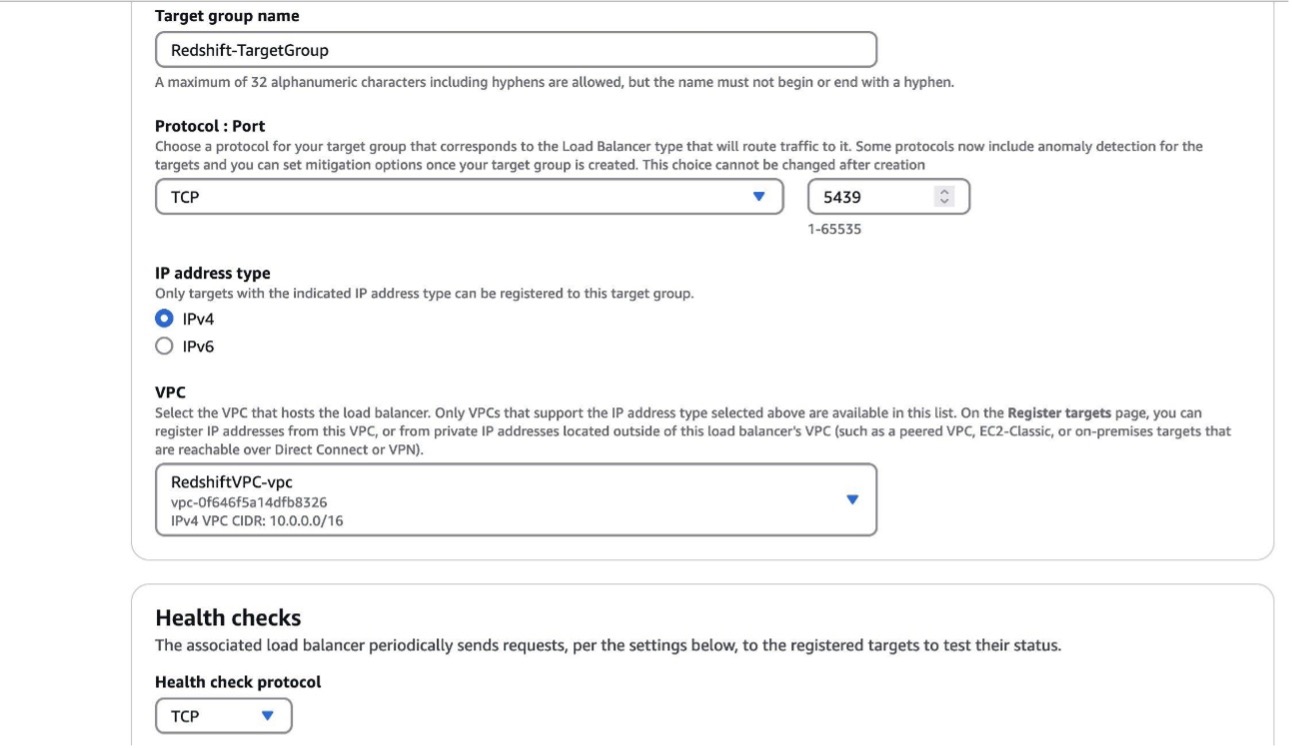
Create a target group

Complete the following steps to create a target group:

  1. On the Amazon EC2 console, under Load balancing in the navigation pane, choose Target groups.
  2. Choose Create target group.
  3. For Choose a target type, select IP addresses.

  1. For Protocol: Port, choose TCP and port 5436 (if your Redshift cluster runs on a different port, change the port accordingly).
  2. For IP address type, select IPv4.
  3. For VPC, choose the same VPC as your Redshift cluster.
  4. Choose Next.

  1. For Enter an IPv4 address from a VPC subnet, enter your Amazon Redshift IP address.

To locate this address, navigate to your cluster details on the Amazon Redshift console, choose the Properties tab, and under Network and security settings, expand VPC endpoint connection details and copy the private address of the network interface. If you’re using Amazon Redshift Serverless, navigate to the workgroup home page. The Amazon Redshift IPv4 addresses can be located in the Network and security section under Data access when you choose VPC endpoint ID.

  1. After you add the IP address, choose Include as pending below, then choose Create target group.

Create a load balancer

Complete the following steps to create a load balancer:

  1. On the Amazon EC2 console, choose Load balancers in the navigation pane.
  2. Choose Create load balancer.
  3. Choose Network.
  4. For Load balancer name, enter a name.
  5. For Scheme, select Internal.
  6. For Load balancer address type, select IPv4.
  7. For VPC, use the VPC that your target group is in.

  1. For Availably Zones, select the Availability Zone where the Redshift cluster is running.
  2. For Security groups, choose the security group you created in the previous step.
  3. For Listener details, add a listener that points to the target group created in the last step:
    1. For Protocol, choose TCP.
    2. For Port, use 5439.
    3. For Default action, choose Redshift-TargetGroup.
  4. Choose Create load balancer.

Make sure that the registered targets in the target group are healthy before proceeding. Also make sure that the target group has a target for all Availability Zones in your AWS Region or the NLB has the Cross-zone load balancing attribute enabled.

In the load balancer’s security setting, make sure that Enforce inbound rules on PrivateLink traffic is off.

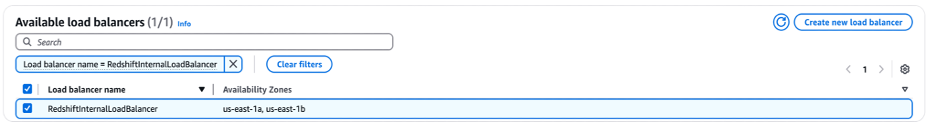
Create an endpoint service

Complete the following steps to create an endpoint service:

  1. On the Amazon VPC console, choose Endpoint services in the navigation pane.
  2. Choose Create endpoint service.
  3. For Load balancer type, choose Network.
  4. For Available load balancers, select the load balancer you created in the last step
  5. From Supported Regions, select an additional region if Data Cloud isn’t hosted in the same AWS region as the Redshift instance.  For additional settings leave Acceptance required.

If this is selected, later, when the Salesforce Data Cloud endpoint is created to connect to the endpoint service, you will need to come back to this page to accept the connection. If not selected, the connection will be built directly.

  1. For Supported IP address type, select IPv4.
  2. Choose Create.

Next, you need to allow Salesforce principals.

  1. After you create the endpoint service, choose Allow principals.
  2. In another browser, navigate to Salesforce Data Cloud Setup.
  3. Under External Integrations, access the new Private Connect menu item.
  4. Create a new private network route to Amazon Redshift.

  1. Copy the principal ID.

  1. Return to the endpoint service creation page.
  2. For Principals to add, enter the principal ID.
  3. Copy the endpoint service name.
  4. Choose Allow principals.

  1. Return to the Salesforce Data Cloud private network configuration page.
  2. For Route Name, enter the endpoint service name.
  3. Choose Save.

The route status should show as Allocating.

If you opted to accept connections in the previous step, you will now need to accept the connection from Salesforce Data Cloud.

  1. On the Amazon VPC console, navigate to the endpoint service.
  2. On the Endpoint connections tab, locate your pending connection request.

  1. Accept the endpoint connection request from Salesforce Data Cloud.

Navigate to the Salesforce Data Cloud setup and wait 30 seconds, then refresh the private connect route so the status shows as Ready.

You can now use this route when creating a connection with Amazon Redshift. For additional details, refer to Part 1 of this series.

Amazon Redshift federation PrivateLink failover

Now that we have discussed how to configure PrivateLink to use with Private Connect for Salesforce Data Cloud, let’s discuss Amazon Redshift federation PrivateLink failover scenarios.

You can choose to deploy your Redshift clusters in three different deployment modes:

  • Amazon Redshift provisioned in a Single-AZ RA3 cluster
  • Amazon Redshift provisioned in a Multi-AZ RA3 cluster
  • Amazon Redshift Serverless

PrivateLink relies on a customer managed NLB connected to service endpoints using IP address target groups. The target group has the IP addresses of your Redshift instance. If there is a change in IP address targets, the NLB target group must be updated to the new IP addresses associated with the service. Failover behavior for Amazon Redshift will differ based on the deployment mode you employ.

This section describes PrivateLink failover scenarios for these three deployment modes.

Amazon Redshift provisioned in a Single-AZ RA3 cluster

RA3 nodes support provisioned cluster VPC endpoints, which decouple the backend infrastructure from the cluster endpoint used for access. When you create or restore an RA3 cluster, Amazon Redshift uses a port within the ranges of 5431–5455 or 8191–8215. When the cluster is set to a port in one of these ranges, Amazon Redshift automatically creates a VPC endpoint in your AWS account for the cluster and attaches network interfaces with a private IP for each Availability Zone in the cluster. For the PrivateLink configuration, you use the IP associated with the VPC endpoint as the target for the frontend NLB. You can identify the IP address of the VPC endpoint on the Amazon Redshift console or by doing a describe-clusters query on the Redshift cluster.

Amazon Redshift will not remove a network interface associated with a VPC endpoint unless you add an additional subnet to an existing Availability Zone or remove a subnet using Amazon Redshift APIs. We recommend that you don’t add multiple subnets to an Availability Zone to avoid disruption. There might be failover scenarios where additional network interfaces are added to a VPC endpoint.

In RA3 clusters, the nodes are automatically recovered and replaced as needed by Amazon Redshift. The cluster’s VPC endpoint will not change even if the leader node is replaced.

Cluster relocation is an optional feature that allows Amazon Redshift to move a cluster to another Availability Zone without any loss of data or changes to your applications. When cluster relocation is turned on, Amazon Redshift might choose to relocate clusters in some situations. In particular, this happens where issues in the current Availability Zone prevent optimal cluster operation or to improve service availability. You can also invoke the relocation function in cases where resource constraints in a given Availability Zone are disrupting cluster operations. When a Redshift cluster is relocated to a new Availability Zone, the new cluster has the same VPC endpoint but a new network interface is added in the new Availability Zone. The new private address should be added to the NLB’s target group to optimize availability and performance.

In the case that a cluster has failed and can’t be recovered automatically, you have to initiate a restore of the cluster from a previous snapshot. This action generates a new cluster with a new DNS name, connection string, and VPC endpoint and IP address for the cluster. You have to update the NLB with the new IP for the VPC endpoint of the new cluster.

Amazon Redshift provisioned in a Multi-AZ RA3 cluster

Amazon Redshift supports Multi-AZ deployments for provisioned RA3 clusters. By using Multi-AZ deployments, your Redshift data warehouse can continue operating in failure scenarios when an unexpected event happens in an Availability Zone. A Multi-AZ deployment deploys compute resources in two Availability Zones, and these compute resources can be accessed through a single endpoint. In the case of a failure of the primary nodes, Multi-AZ clusters will make secondary nodes primary and deploy a new secondary stack in another Availability Zone. The following diagram illustrates this architecture.

Multi-AZ clusters deploy VPC endpoints that point to network interfaces in two Availability Zones, which should be configured as a part of the NLB target group. To configure the VPC endpoints in the NLB target group, you can identify the IP addresses of the VPC endpoint using the Amazon Redshift console or by doing a describe-clusters query on the Redshift cluster. In a failover scenario, VPC endpoint IPs will not change and the NLB doesn’t require an update.

Amazon Redshift will not remove a network interface associated with a VPC endpoint unless you add an additional subnet in to an existing Availability Zone or remove a subnet using Amazon Redshift APIs. We recommend that you don’t add multiple subnets to an Availability Zone to avoid disruption.

Amazon Redshift Serverless

Redshift Serverless provides managed infrastructure. You can perform the get-workgroup query to get the workgroup’s VpcEndpoint IPs. IPs should be configured in the target group of the PrivateLink NLB. Because this is a managed service, the failover is managed by AWS. During the event of an underlying Availability Zone failure, the workgroup might get a new set of IPs. You can frequently query the workgroup configuration or DNS record for the Redshift cluster to check if IP addresses have changed and update the NLB accordingly.

Automating IP address management

In scenarios where Amazon Redshift operations might change the IP address of the endpoint needed for Amazon Redshift connectivity, you can automate the update of NLB network targets by monitoring the results for cluster DNS resolution, using describe-cluster or get-workgroup queries, and using an AWS Lambda function to update the NLB target group configuration.

You can periodically (on a schedule) query the DNS of the Redshift cluster for IP address resolution. Use a Lambda function to compare and update the IP target groups for the NLB. For an example of this solution, see Hostname-as-Target for Network Load Balancers.

For legacy DS2 clusters where the IP address of the leader node must be explicitly monitored, you can configure Amazon CloudWatch metrics to monitor the HealthStatus of the leader node. You can configure the metric to trigger an alarm, which alerts an Amazon Simple Notification Service (Amazon SNS) topic and invokes a Lambda function to reconcile the NLB target group.

For backup and restore patterns, you can create a rule in Amazon EventBridge triggered on the RestoreFromClusterSnapshot API action, which invokes a Lambda function to update the NLB with the new IP addresses of the cluster.

For a cluster relocation pattern, you can trigger an event based on the Amazon Redshift ModifyCluster availability-zone-relocation API action.

Conclusion

In this post, we discussed how to use AWS endpoint services to improve data security with Private Connect for Salesforce Data Cloud. If you are currently using the Salesforce Data Cloud zero-copy integration with Amazon Redshift, we recommend you follow the steps provided in this post to make the network connection between Salesforce and AWS secure. Reach out to your Salesforce and AWS support teams if you need additional support to implement this solution.


About the authors

Yogesh Dhimate is a Sr. Partner Solutions Architect at AWS, leading technology partnership with Salesforce. Prior to joining AWS, Yogesh worked with leading companies including Salesforce driving their industry solution initiatives. With over 20 years of experience in product management and solutions architecture Yogesh brings unique perspective in cloud computing and artificial intelligence.

Avijit Goswami is a Principal Solutions Architect at AWS specialized in data and analytics. He supports AWS strategic customers in building high-performing, secure, and scalable data lake solutions on AWS using AWS managed services and open source solutions. Outside of his work, Avijit likes to travel, hike, watch sports, and listen to music.

Ife Stewart is a Principal Solutions Architect in the Strategic ISV segment at AWS. She has been engaged with Salesforce Data Cloud over the last 2 years to help build integrated customer experiences across Salesforce and AWS. Ife has over 10 years of experience in technology. She is an advocate for diversity and inclusion in the technology field.

Mike Patterson is a Senior Customer Solutions Manager in the Strategic ISV segment at AWS. He has partnered with Salesforce Data Cloud to align business objectives with innovative AWS solutions to achieve impactful customer experiences. In his spare time, he enjoys spending time with his family, sports, and outdoor activities.

Drew Loika is a Director of Product Management at Salesforce and has spent over 15 years delivering customer value via data platforms and services. When not diving deep with customers on what would help them be more successful, he enjoys the acts of making, growing, and exploring the great outdoors.

Adopting Amazon Q Developer in Enterprise Environments

Post Syndicated from Rene-Martin Tudyka original https://aws.amazon.com/blogs/devops/adopting-amazon-q-developer-in-enterprise-environments/

Increasing developer productivity has been a persistent challenge for senior leaders over the past decades. With the rise of generative artificial intelligence (AI), a new wave of innovation is transforming how software teams work. Generative AI tools like Amazon Q Developer are emerging as game-changers, supporting developers across the entire software development lifecycle. But how are large-scale organizations successfully adopting this AI-assisted approach? This document shares good practices I have discovered through working with enterprise customers navigating this technological transformation.

A common misperception still is that a developer is more productive when they write code faster. But a median developer spends less than one hour per day writing code, as a study conducted by software.com in 2022 shows. This makes clear that there are other aspects to consider when it comes to building an application and running it in production. Generative AI tools for developers, such as Amazon Q Developer, started as coding companions that provided inline completions. As the technology evolved, Amazon Q Developer is now able to support developers across the entire software development life cycle.

The Change Challenge

Generative AI offers new and interesting ways for developers to solve challenges and to support them in their daily work. But taking advantage of those opportunities takes some time. It introduces a noticeable change to their familiar ways of working and therefore it is much about forming a new habit. This, according to science, usually takes a minimum of two months. Teams need the space and permission to play with this new approach and to find out what works best for them. Expecting them to adopt a new way of working while expecting the same (or higher) level of output at the same time will only lead to teams falling back to what they know works. For customers that successfully have adopted Amazon Q Developer I have seen them reducing the delivery expectations to give space to learn, and having required teams to share learnings in return.

Additionally, as in any other large change project there is a significant cultural aspect to consider. If people feel intrinsically convinced by the value and benefits of an AI-supported approach to software engineering they will use it. “Simply ordering from above” will not help making an adoption successful. But building community, experimenting, learning, and sharing successes will. “Culture eats strategy for breakfast”, as the management visionary Peter Drucker said.

Keeping that in mind it is clear that there is no one-size-fits-all prescriptive way of successfully introducing generative AI tools for developers in your organization. It very much depends on your individual culture, goals, challenges, people, skills, and technology stack for example. However, there are a number of principles and good practices that work well with several of our large-scale customers who have successfully adopted Amazon Q Developer.

Best Practices for Successful Adoption

The following illustration describes the change management cycle and recommended activities for adopting AI-assisted software development.

The change management cycle – align, plan, roll out, reflect and repeat

Figure 1. The change management cycle

1. Secure Top-Down Commitment

Secure executive buy-in for adopting AI-assisted software development because this is a powerful sign for the organization. It helps to remove roadblocks and to promote successes across the organization. An executive sponsor links the adoption of AI-assisted software development to the strategic goals of the organization, will help resolving prioritization and capacity conflicts. Invite the sponsor to a kick-off meeting. Include them for the discussion of goals and success criteria, and keep them updated on progress, success stories, and challenges.

2. Become Clear on Goals and Success Criteria

Simply rolling out Generative AI tools to a large developer base won’t be enough. You need to be clear what you expect from such an adoption for your organization, for your developers, and for your business. It is important for you to understand your organization’s pain points from a developer experience perspective and how they affect your development productivity. These likely differ between different personas, like Software Developers and DevOps Engineers. For example, are your applications lacking test coverage or is your code lacking documentation, which creates a maintenance burden, and makes it difficult to onboard new developers? Is handling legacy code risky and time-consuming so that you avoid necessary upgrades because of the complexity and effort? Is troubleshooting applications locally or in production eating up your developers’ time? Or are you facing challenges caused by hard-to-find security issues in the code? What is it that you want to achieve by introducing an AI-assisted development approach, and why?

3. Establish Ownership

Adopting a new approach like the use of generative AI in software development at scale leads to many change management and coordination tasks. Those are related to getting access to the tool, enablement for new users, budget planning, measuring success and creating transparency on problems, creating momentum and making sure the adoption sustains, amongst others. Therefore, introducing a Customer Champion as a leader who coordinates the business and technology related aspects of the adoption is a common approach. They will connect the strategic goals of the organization with the tactical activities necessary for the implementation. If your adoption is spanning multiple different business units with larger developer bases consider establishing this role for each of them, forming a team that collaborates across your whole organization. Key responsibilities of the Customer Champion are to bring the right people together to successfully work on the adoption, to create transparency on status, and to address impediments early on.

4. Introduce Metrics

Once you have gained clarity on the specific pain points and goals for your organization, the next step is to determine the appropriate metrics to measure the success of your efforts. For example, you can measure the impact of using Amazon Q Developer on onboarding new developers by tracking the time to first commit against a previously established baseline average. Comparing the time it takes to complete certain tasks – like writing and integrating code, fixing bugs, setting up or upgrading environments, the time it takes to build a new feature, or by comparing sprint velocity before and after the introduction of Amazon Q Developer will give you further indications. But keep in mind that there is ambiguity in these metrics because they are impacted by different factors.

Focusing on developer experience and productivity, monitor the development of your established measurement framework, like DORA, SPACE, or GSM. SPACE in particular, with its “Satisfaction & Well-Being” dimension, pays close attention to how software developers perceive their work and how satisfied they are with their own productivity. Tools like Amazon Q Developer have shown a positive effect here, as for example a McKinsey study shows. They help to free developers from tasks that are perceived as toil, like repetitive and boring grunt work that doesn’t necessarily bring business value. To measure this impact on perceived productivity, customers sometimes design simple surveys, asking developers questions like “in percentage, how would you estimate the impact of using Amazon Q Developer on your productivity” or “on a scale from 1-5, how is Amazon Q Developer impacting the satisfaction with your day-to-day work?”

As a last dimension, understanding the general usage of Amazon Q Developer across your organization is important. Monitor the number active subscriptions, accepted code recommendations, or the number of executed security scans from the Amazon Q Developer dashboard. That way you will get an understanding for the acceptance of the tool in your developer base. Correlate this information with the success metrics you defined.

5. Start Small

When “rolling out” an AI-assisted software development approach, keep the technology adoption lifecycle and Everett Roger’s bell curve in mind. It describes that adoption of a new technology usually starts with a few “innovators”, followed by a small fraction of “early adopters”. Only if those early groups demonstrate convincing success, the majority of users will follow the adoption. To settle on this model will help you making the adoption of AI-assisted development successful in your organization.

Start small. Identify your tech innovators, or champions, who are enthusiastic to support the introduction of Amazon Q Developer and to advocate the approach in your organization. With them, build a team or a Center of Excellence (COE) that will help with identifying early adopters across your development teams, building technical and enablement foundations for onboarding users, creating roll-out plans, and evangelizing and sustaining the adoption. The champions will act as a bridge between your adoption program team and your users. They can provide insights and feedback on the adoption and come up with recommendations.

6. Create Momentum

Now that you have your foundations in place it is time to create momentum and onboard your early adopters to Amazon Q Developer. Start with a communication plan to raise awareness, to share updates and success stories, and to collect feedback from the users. You will need to create training material covering organization-specific resources (how to get access, for example, or which communication channels and contact points exist), user guides, tutorials, and pointers to relevant documentation and online resources. Consider creating your own prompt library, documenting prompts for Amazon Q Developer that your users find particularly helpful. There are community projects like promptz.dev that can deliver inspiration. Especially for new users this will have a lot of value for getting up to speed.

Consider how to integrate learning pathways with your organization’s learning platform moving forward. These should include the company-specific experience and knowledge you collect. In addition, it might be helpful to integrate external offers, like classroom trainings or workshop formats offered by AWS.

Hands-on technical enablement workshops will help your early adopters jumpstarting their experience. AWS offers multiple formats that can be tailored to your individual context. These include service deep-dives with Amazon Q Developer specialists, Immersion Days and hackathon support for teams to hands-on experience the tool in a guided, interactive format, or joined proof-of-value engagements. Your AWS account team will provide you more information.

7. Sustain and Scale Adoption

At that point you will have established Amazon Q Developer among an initial segment of your developer base. However, keeping Roger’s adoption curve in mind the largest part of the adoption still lies ahead of you. To facilitate the it across your whole organization, focus on delivering enablement workshops for the teams to be onboarded. These will be led by your champions and incorporate your organization-specific practices and knowledge.

To sustain the adoption, make sure the existing user base stays active. Continue offering exchange and support, collecting feedback, updating your enablement material, sharing updates on the latest developments for Amazon Q Developer, and reviewing your metrics. Create visibility across your organization for the accomplishments and positive experiences. Let user talk about the impact Amazon Q Developer has on their work. This will help building momentum. Nurture community building around your users of AI-assisted development.

Establish regular office hours with your champions for providing support and enablement to your users of Amazon Q Developer. This will facilitate the continuous gathering of feedback to improve documentation and enablement materials, collect and promote success stories, and validate the adoption approach. Additionally, establish a consistent communications and reporting cadence to keep all relevant stakeholders informed of key metrics, updates, feedback, and success stories. This ensures the alignment of the adoption of AI-assisted development with your strategic goals and expectations.

8. Inspect and Adapt

In addition, keep reflecting on the goals and metrics you came up with from a strategic perspective. Are they developing in the right direction? Are your pain points still the same? Should you move your focus to different aspects of the software development life cycle? And how might new capabilities of Amazon Q Developer support your goals?

Conclusion

By following the outlined approach, large organizations can successfully navigate the challenges of adopting Amazon Q Developer. The approach addresses technical, cultural, and organizational aspects of the adoption, increasing the likelihood of realizing the full potential of AI-assisted development across the enterprise.

If you are looking for advice or support during your adoption journey, your AWS Account Team will connect you with experts on Amazon Q Developer, provide you information on training and enablement, and support you with setting up a successful rollout program for your organization. To learn more about how Amazon Q Developer’s capabilities support the whole software development lifecycle, visit the product page or have a look at the documentation.

About the Author

Rene-Martin Tudyka is a Senior Customer Solutions Manager at AWS and provides guidance and support for enterprise customers on their cloud maturity journey. He has a long background in developing highly performant IT organizations and in successful large-scale cloud adoption.

Enhancing cloud security in AI/ML: The little pickle story

Post Syndicated from Nur Gucu original https://aws.amazon.com/blogs/security/enhancing-cloud-security-in-ai-ml-the-little-pickle-story/

As AI and machine learning (AI/ML) become increasingly accessible through cloud service providers (CSPs) such as Amazon Web Services (AWS), new security issues can arise that customers need to address. AWS provides a variety of services for AI/ML use cases, and developers often interact with these services through different programming languages. In this blog post, we focus on Python and its pickle module, which supports a process called pickling to serialize and deserialize object structures. This functionality simplifies data management and the sharing of complex data across distributed systems. However, because of potential security issues, it’s important to use pickling with care (see the warning note in pickle — Python object serialization). In this post, we’re going to show you ways to build secure AI/ML workloads that use this powerful Python module, ways to detect that it’s in use that you might not know about, and when it might be getting abused, and finally highlight alternative approaches that can help you avoid these issues.

Quick tips

Understanding insecure pickle serialization and deserialization in Python

Effective data management is crucial in Python programming, and many developers turn to the pickle module for serialization. However, issues can arise when deserializing data from untrusted sources. The Python bytestream that pickling uses, is proprietary to Python. Until it’s unpickled, the data in the bytestream can’t be thoroughly evaluated. This is where security controls and validation become critical. Without proper validation, there’s a risk that an unauthorized user could inject unexpected code, potentially leading to arbitrary code execution, data tampering, or even unintended access to a system. In the context of AI model loading, secure deserialization is particularly important—it helps prevent outside parties from modifying model behavior, injecting backdoors, or causing inadvertent disclosure of sensitive data.

Throughout this post, we will refer to pickle serialization and deserialization collectively as pickling. Similar issues can be present in other languages (for example, Java and PHP) when untrusted data is used to recreate objects or data structures, resulting in potential security issues such as arbitrary code execution, data corruption, and unauthorized access.

Static code analysis compared to dynamic testing for detecting pickling

Security code reviews, including static code analysis, offer valuable early detection and thorough coverage of pickling-related issues. By examining source code (including third-party libraries and custom code) before deployment, teams can minimize security risks in a cost-effective way. Tools that provide static analysis can automatically flag unsafe pickling patterns, giving developers actionable insights to address issues promptly. Regular code reviews also help developers improve secure coding skills over time.

While static code analysis provides a comprehensive white-box approach, dynamic testing can uncover context-specific issues that only appear during runtime. Both methods are important. In this post, we focus primarily on the role of static code analysis in identifying unsafe pickling.

Tools like Amazon CodeGuru and Semgrep are effective at detecting security issues early. For open source projects, Semgrep is a great option to maintain consistent security checks.

The risks of insecure pickling in AI/ML

Pickling issues in AI/ML contexts can be especially concerning.

  • Invalidated object loading: AI/ML models are often serialized for future use. Loading these models from untrusted sources without validation can result in arbitrary code execution. Libraries such as pickle, joblib, and some yaml configurations allow serialization but must be handled securely.
    • For example: If a web application stores user input using pickle and unpickles it later with no validation, an unauthorized user could craft a harmful payload that executes arbitrary code on the server.
  • Data integrity: The integrity of pickled data is critical. Unexpectedly crafted data could corrupt models, resulting in incorrect predictions or behaviors, which is especially concerning in sensitive domains such as finance, healthcare, and autonomous systems.
    • For example: A team updates its AI model architecture or preprocessing steps but forgets to retrain and save the updated model. Loading the old pickled model under new code might trigger errors or unpredictable outcomes.
  • Exposure of sensitive information: Pickling often includes all attributes of an object, potentially exposing sensitive data such as credentials or secrets.
    • For example: An ML model might contain database credentials within its serialized state. If shared or stored without precautions, an unauthorized user who unpickles the file might gain unintended access to these credentials.
  • Insufficient data protection: When sent across networks or stored without encryption, pickled data can be intercepted, leading to inadvertent disclosure of sensitive information.
    • For example: In a healthcare environment, a pickled AI model containing patient data could be transmitted over an unsecured network, enabling an outside party to intercept and read sensitive information.
  • Performance overhead: Pickling can be slower than other serialization formats (such as, JSON or Protocol Buffers), which can affect ML and large language model (LLM) applications when inference speed is critical.
    • For example: In a real-time natural language processing (NLP) application using an LLM, heavy pickling or unpickling operations might reduce responsiveness and degrade the user experience.

Detecting unsafe unpickling with static code analysis tools

Static code analysis (SCA) is a valuable practice for applications dealing with pickled data, because it helps detect insecure pickling before deployment. By integrating SCA tools into the development workflow, teams can spot questionable deserialization patterns as soon as code is committed. This proactive approach reduces the risk of events involving unexpected code execution or unintended access due to unsafe object loading.

For instance, in a financial services application where objects are routinely pickled, a SCA tool can scan new commits to detect unvalidated unpickling. If identified, the development team can quickly address the issue, protecting both the integrity of the application and sensitive financial data.

Patterns in the source code

There are various ways to load a pickle object in Python. In this context, methods for detection can be tailored for secure coding habits and needed package dependencies. Many Python libraries include a function to load pickle objects. An effective approach can be to catalog all Python libraries used in the project, then create custom rules in your static code analysis tool to detect unsafe pickling or unpickling within those libraries.

CodeGuru and other static analysis tools continue to evolve their capability to detect unsafe pickling patterns. Organizations can use these tools and create custom rules to identify potential security issues in AI/ML pipelines.

Let’s define the steps for creating a safe process for addressing pickling issues:

  1. Generate a list of all the Python libraries that are used in your repository or environment.
  2. Check the static code analysis tool in your pipeline for current rules and the ability to add custom rules. If the tool is capable of discovering all the libraries used in your project, you can rely on it. However, if it’s not able to discover all the libraries used in your project, you should consider adding user-provided custom rules in your static code analysis tool.
  3. Most of the issues can be identified with well-designed, context-driven patterns in the static code analysis tool. For addressing the pickling issues, you need to identify pickling and unpickling functions.
  4. Implement and test the custom rules to verify full coverage of pickling and unpickling risks. Let’s identify patterns for a few libraries:
    • NumPy can efficiently pickle and unpickle arrays; useful for scientific computing workflows requiring serialized arrays. To catch potential unsafe pickle usage in NumPy, custom rules could target patterns like:
      import numpy as np
      data = np.load('data.npy', allow_pickle=True)

    • npyfile is a utility for loading NumPy arrays from pickled files. You can add the following patterns to your custom rules to discover potentially unsafe pickle object usage.
      import npyfile
      data = npyfile.load('example.pkl')

    • pandas can pickle and unpickle DataFrames using pickle, allowing for efficient storage and retrieval of tabular data. You can add the following patterns to your custom rules to discover potentially unsafe pickle object usage.
      import pandas as pd
      df = pd.read_pickle('dataframe.pkl')

    • joblib is often used for pickling and unpickling Python objects that involve large data, especially NumPy arrays, more efficiently than standard pickle. You can add the following patterns to your custom rules to discover potentially unsafe pickle object usage.
      from joblib import load
      data = load('large_data.pkl')

    • Scikit-learn provides joblib for pickling and unpickling objects and is particularly useful for models. You can add the following patterns to your custom rules to discover potentially unsafe pickle object usage.
      from sklearn.externals import joblib
      data = joblib.load('example.pkl')

    • PyTorch provides utilities for loading pickled objects that are especially useful for ML models and tensors. You can add the following patterns to your custom rule format to discover potentially unsafe pickle object usage.
      import torch
      data = torch.load('example.pkl')

By searching for these functions and parameters in code, you can set up targeted rules that highlight potential issues with pickling.

Effective mitigation

Addressing pickling issues requires not only detection, but also clear guidance on remediation. Consider recommending more secure formats or validations where possible as follows:

  • PyTorch
    • Use Safetensors to store tensors. If pickling remains necessary, add integrity checks (for example, hashing) for serialized data.
  • pandas
    • Verify data sources and integrity when using pd.read_pickle. Encourage safer alternatives (for example, CSV, HDF5, or Parquet) to help avoid pickling risks.
  • scikit-learn (via joblib)
    • Consider Skops for safer persistence. If switching formats isn’t feasible, implement strict validation checks before loading.
  • General advice
    • Identify safer libraries or methods whenever possible.
    • Switch to formats such as CSV or JSON for data, unless object-specific serialization is absolutely required.
    • Perform source and integrity checks before loading pickle files—even those considered trusted.

Example

The following is an example implementation that shows safe pickle implementation as a representation of the preceding information.

import io
import base64
import pickle
import boto3
import numpy as np
from cryptography.fernet import Fernet

###############################################################################
# 1) RESTRICTED UNPICKLER
###############################################################################
#
# By default, pickle can execute arbitrary code when loading. Here we implement
# a custom Unpickler that only allows certain safe modules/classes. Adjust this
# to your application's requirements.
#

class RestrictedUnpickler(pickle.Unpickler):
    """
    Restricts unpickling to only the modules/classes we explicitly allow.
    """
    allowed_modules = {
        "numpy": set(["ndarray", "dtype"]),
        "builtins": set(["tuple", "list", "dict", "set", "frozenset", "int", "float", "bool", "str"])
    }

    def find_class(self, module, name):
        if module in self.allowed_modules:
            if name in self.allowed_modules[module]:
                return super().find_class(module, name)
        # If not allowed, raise an error to prevent arbitrary code execution.
        raise pickle.UnpicklingError(f"Global '{module}.{name}' is forbidden")

def restricted_loads(data: bytes):
    """Helper function to load pickle data using the RestrictedUnpickler."""
    return RestrictedUnpickler(io.BytesIO(data)).load()

###############################################################################
# 2) AWS KMS & ENCRYPTION HELPERS
###############################################################################

def generate_data_key(kms_key_id: str, region: str = "us-east-1"):
    """
    Generates a fresh data key using AWS KMS. 
    Returns (plaintext_key, encrypted_data_key).
    """
    kms_client = boto3.client("kms", region_name=region)
    response = kms_client.generate_data_key(KeyId=kms_key_id, KeySpec='AES_256')
    
    # Plaintext data key (use to encrypt the pickle data locally)
    plaintext_key = response["Plaintext"]
    # Encrypted data key (store along with your ciphertext)
    encrypted_data_key = response["CiphertextBlob"]
    return plaintext_key, encrypted_data_key

def decrypt_data_key(encrypted_data_key: bytes, region: str = "us-east-1"):
    """
    Decrypts the encrypted data key via AWS KMS, returning the plaintext key.
    """
    kms_client = boto3.client("kms", region_name=region)
    response = kms_client.decrypt(CiphertextBlob=encrypted_data_key)
    return response["Plaintext"]

def build_fernet_key(plaintext_key: bytes) -> Fernet:
    """
    Construct a Fernet instance from a 32-byte data key.
    Fernet requires a 32-byte key *encoded* in URL-safe base64.
    """
    if len(plaintext_key) < 32:
        raise ValueError("Data key is smaller than 32 bytes; cannot build a Fernet key.")
    fernet_key = base64.urlsafe_b64encode(plaintext_key[:32])
    return Fernet(fernet_key)

###############################################################################
# 3) MAIN LOGIC
###############################################################################

def upload_pickled_data_s3(
    numpy_obj: np.ndarray,
    bucket_name: str,
    s3_key: str,
    kms_key_id: str,
    region: str = "us-east-1"
):
    """
    Pickle a numpy object, encrypt it locally, and upload the ciphertext + 
    encrypted data key to S3.
    """
    # 1. Generate data key from KMS
    plaintext_key, encrypted_data_key = generate_data_key(kms_key_id, region)
    
    # 2. Build Fernet from plaintext data key
    fernet = build_fernet_key(plaintext_key)
    
    # 3. Serialize the numpy object with pickle
    pickled_data = pickle.dumps(numpy_obj, protocol=pickle.HIGHEST_PROTOCOL)
    
    # 4. Encrypt the pickled data
    encrypted_data = fernet.encrypt(pickled_data)
    
    # 5. Upload to S3 along with the encrypted data key (in metadata)
    s3_client = boto3.client("s3", region_name=region)
    s3_client.put_object(
        Bucket=bucket_name,
        Key=s3_key,
        Body=encrypted_data,
        Metadata={
            "encrypted_data_key": base64.b64encode(encrypted_data_key).decode("utf-8")
        }
    )
    print(f"Encrypted pickle uploaded to s3://{bucket_name}/{s3_key}")

def download_and_unpickle_data_s3(
    bucket_name: str,
    s3_key: str,
    region: str = "us-east-1"
) -> np.ndarray:
    """
    Download the ciphertext and the encrypted data key from S3. Decrypt the data 
    key with KMS, use it to decrypt the pickled data, then load with a restricted 
    unpickler for safety.
    """
    s3_client = boto3.client("s3", region_name=region)
    
    # 1. Get object from S3
    response = s3_client.get_object(Bucket=bucket_name, Key=s3_key)
    
    # 2. Extract the encrypted data key from metadata
    metadata = response["Metadata"]
    encrypted_data_key_b64 = metadata.get("encrypted_data_key")
    if not encrypted_data_key_b64:
        raise ValueError("Missing encrypted_data_key in S3 object metadata.")
    
    encrypted_data_key = base64.b64decode(encrypted_data_key_b64)
    
    # 3. Decrypt data key via KMS
    plaintext_key = decrypt_data_key(encrypted_data_key, region)
    fernet = build_fernet_key(plaintext_key)
    
    # 4. Decrypt the pickled data
    encrypted_data = response["Body"].read()
    decrypted_pickled_data = fernet.decrypt(encrypted_data)
    
    # 5. Use restricted unpickler to load the numpy object
    numpy_obj = restricted_loads(decrypted_pickled_data)
    
    return numpy_obj

###############################################################################
# DEMO USAGE
###############################################################################

if __name__ == "__main__":
    # --- Replace with your actual values ---
    KMS_KEY_ID = "arn:aws:kms:us-east-1:123456789012:key/your-kms-key-id"
    BUCKET_NAME = "your-secure-bucket"
    S3_OBJECT_KEY = "encrypted_npy_demo.bin"
    AWS_REGION = "us-east-1"  # or region of your choice
    
    # Example numpy array
    original_array = np.random.rand(2, 3)
    print("Original Array:")
    print(original_array)
    
    # Upload (pickle + encrypt) to S3
    upload_pickled_data_s3(
        numpy_obj=original_array,
        bucket_name=BUCKET_NAME,
        s3_key=S3_OBJECT_KEY,
        kms_key_id=KMS_KEY_ID,
        region=AWS_REGION
    )
    
    # Download (decrypt + unpickle) from S3
    retrieved_array = download_and_unpickle_data_s3(
        bucket_name=BUCKET_NAME,
        s3_key=S3_OBJECT_KEY,
        region=AWS_REGION
    )
    
    print("\nRetrieved Array:")
    print(retrieved_array)
    
    # Verify integrity
    assert np.allclose(original_array, retrieved_array), "Arrays do not match!"
    print("\nSuccess! The retrieved array matches the original array.")

Conclusion

With the rapid expansion of cloud technologies, integrating static code analysis into your AI/ML development process is increasingly important. While pickling offers a powerful way to serialize objects for AI/ML and LLM applications, you can mitigate potential risks by applying manual secure code reviews, setting up automated SCA with custom rules, and following best practices such as using alternative serialization methods or verifying data integrity.

When working with ML models on AWS, see the AWS Well-Architected Framework’s Machine Learning Lens for guidance on secure architecture and recommended practices. By combining these approaches, you can maintain a strong security posture and streamline the AI/ML development lifecycle.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
 

Nur Gucu
Nur Gucu

Nur is a Security Engineer at Amazon with 10 years of offensive security expertise, specializing in generative AI security, security architecture, and offensive testing. Nur has developed security products at startups and banks, and has created frameworks for emerging technologies. She brings practical experience to solve complex AI security challenges, and yet believes as many as six impossible things before breakfast.
Matt Schwartz
Matt Schwartz

Matt is an Amazon Principal Security Engineer specializing in generative AI security, risk management, and cloud computing expertise. His two-decade expertise enables organizations to implement advanced AI while maintaining strict security protocols. Matthew develops strategic frameworks that safeguard critical assets and ensure compliance in the evolving digital landscape, securing complex systems during transformations.

Building a voice interface for generative AI assistants

Post Syndicated from Reynaldo Hidalgo original https://aws.amazon.com/blogs/messaging-and-targeting/building-voice-interface-for-genai-assistant/

Generative AI is revolutionizing how businesses interact with their customers through natural conversational interfaces. While organizations can implement AI assistants across various channels, phone calls remain a preferred method for many customers seeking support or information.

We’ll demonstrate how to create a voice interface for your existing Amazon Bedrock generative AI assistant, enabling customers to engage in phone-based conversations with your AI implementation.

Solution overview

Using Workflow Studio for Amazon Web Services (AWS) Step Functions, we built a voice communication interface that connects with the Amazon Nova Micro model in Amazon Bedrock (Figure 1). The demo application uses the base model to enable open-ended questions. Organizations can implement either Amazon Bedrock Agents or Flows to address specific business requirements.

A Step Functions workflow diagram illustrating a voice communication system integrated with Amazon Bedrock. The workflow shows a sequential process starting with call handling, followed by parallel branches: one for managing hold music and another for processing voice input through Amazon Transcribe and Amazon Nova Micro model. The diagram demonstrates the complete call flow from initial welcome message through question-answer cycles to call completion.

Figure 1 – Step Functions workflow that enables voice communication to a generative AI assistant

How it works:

  1. Inbound call arrives
  2. System plays welcome message
  3. System asks caller for questions
  4. Voice recording starts, stopping when silence is detected
  5. Parallel flows begin:
    • First flow
      1. Plays some music while the caller is on-hold
    • Second flow
      1. Transcribes the recording using Amazon Transcribe
      2. Sends transcribed question to the Amazon Nova Micro model in Amazon Bedrock
      3. Upon receiving the response, stops the on-hold music
  6. Text-to-speech plays the model’s answer
  7. System asks for additional questions and loops to Step 4 or ends the call

 Expanded capabilities and optimizations

These are potential improvements, additional functionalities, and advanced features that can enhance the demo application:

  • The transcription component is interchangeable with any speech-to-text generative AI model (including Whisper Large V3 Turbo on Amazon Bedrock Marketplace)
  • The PSTN audio service RecordAudio Action can be tuned to adjust silence duration and background noise levels
  • Enabling the PSTN audio service VoiceFocus feature to improve call clarity by reducing background noise and enhancing voice quality
  • PSTN audio service Session Initiation Protocol (SIP) media applications can also handle calls through SIP trunking by using Amazon Chime SDK Voice Connector, streamlining integration with existing phone systems
  • The UpdateSipMediaApplicationCall API is a PSTN audio service feature that lets you regain call control and apply new actions during active calls
  • Parallel workflow states allow user-friendly handling of API service calls by playing music during processing
  • PSTN audio service provides pay-per-minute rates with serverless, scalable telephony infrastructure

Deploying the solution

 The following steps allow you to deploy the voice communication interface workflow (Figure 1) together with the supporting serverless architecture for Step Functions and PSTN audio service integration. In a previous blog, we demonstrated how combining Step Functions and Amazon Chime SDK PSTN audio service streamlines the development of reliable telephony applications through a visual workflow design.

 Prerequisites:

  1. AWS Management Console access
  2. Node.js and npm installed
  3. AWS Command Line Interface (AWS CLI) installed and configured
  4. Enable access to the Amazon Nova Micro model through the Amazon Bedrock console

 Walkthrough:

The AWS Cloud Development Kit (AWS CDK) project on the AWS GitHub repository will deploy the following resources:

  • phoneNumberBedrock – Provisioned phone number for the demo application
  • sipMediaApp – SIP media application that routes calls to lambdaProcessPSTNAudioServiceCalls
  • sipRule – SIP rule that directs calls from phoneNumberBedrock to sipMediaApp
  • lambdaProcessPSTNAudioServiceCalls – AWS Lambda function for call processing
  • roleLambdaProcessPSTNAudioServiceCalls – AWS Identity and Access Management (IAM) Role for lambdaProcessPSTNAudioServiceCalls
  • stepfunctionBedrockWorkflow – Step Functions workflow for the telephony application
  • roleStepfuntionBedrockWorkflow – IAM Role for stepfunctionBedrockWorkflow
  • s3BucketApp – Amazon Simple Storage Service (Amazon S3) bucket for storing customer questions recordings
  • s3BucketPolicy – IAM Policy granting PSTN audio service access to s3BucketApp
  • lambdaAudioTranscription – Lambda function for audio transcription
  • lambdaLayerForTranscription – Lambda layer required for lambdaAudioTranscription
  • roleLambdaAudioTranscription – IAM Role for lambdaAudioTranscription

Follow these steps to deploy the CDK stack:

  1. Clone the repository.
git clone https://github.com/aws-samples/sample-chime-sdk-bedrock-voice-interface
cd sample-chime-sdk-bedrock-voice-interface
npm install
  1. Bootstrap the stack.
#default AWS CLI credentials are used, otherwise use the –-profile parameter
#provide the <account-id> and <region> to deploy this stack
cdk bootstrap aws://<account-id>/<region>
  1. Deploy the stack.
#default AWS CLI credentials are used, otherwise use the –-profile parameter
#phoneAreaCode: the United States area code used to provision the phone number
cdk deploy –-context phoneAreaCode=NPA
  1. Call the provisioned phone number to test the sample application.

Cleaning up:

To clean up this demo, execute:

cdk destroy

Conclusion

We demonstrated how organizations can add voice capabilities to their existing generative AI implementations using Amazon Bedrock. The solution enables customers to interact with AI assistants through traditional phone calls, expanding accessibility and user engagement. The demo application showcases an architecture combining AWS Step Functions and Amazon Chime SDK PSTN audio service, delivering natural voice conversations with AI models through quick deployment using visual workflows.

Organizations benefit from cost optimization with pay-per-minute pricing, enterprise-ready telephony integration through PSTN or SIP trunking, and automatic scaling to match customer demand. This foundation enables businesses to build practical AI applications ranging from all day customer service agents, to multi-language support services, and knowledge base assistants. By following this solution, you can quickly extend your generative AI investments to voice channels, providing more value to your customers while maintaining operational efficiency.

Contact an AWS Representative to know how we can help accelerate your business.

Use AWS service reference information to automate policy management workflows

Post Syndicated from Ramesh Rajan original https://aws.amazon.com/blogs/security/use-aws-service-reference-information-to-automate-policy-management-workflows/

Amazon Web Services (AWS) provides service reference information in JSON format to help you automate policy management workflows. With the service reference information, you can access available actions across AWS services from machine-readable files. The service reference information helps to address a key customer need: keeping up with the ever-growing list of services and actions in AWS. As new services launch and existing services expand their capabilities, you can now conveniently identify and incorporate available actions, resources, and condition keys for each AWS service into your policy authoring and validation workflows. As your business expands and your AWS footprint grows, you might decide to automate your policy management workflows. With the service authorization reference, you can build custom tools to make it easier to evaluate and use new actions, resources, and condition keys that AWS services introduce.

Getting started with service reference information

The service reference information is static information about the actions, resources, and condition keys available for each service in AWS. To obtain the list of AWS services for which reference information is available, go to the following URL:
https://servicereference.us-east-1.amazonaws.com/v1/service-list.json

This URL endpoint provides a JSON file that contains an up-to-date catalog of AWS services with available reference information. By querying this endpoint, you can retrieve the most current list of services supported by the AWS Service Reference Information feature.

To retrieve the list of actions, resources, and condition keys for a specific AWS service, go to the following URL:
https://servicereference.us-east-1.amazonaws.com/v1/<service-name>/<service-name>.json

Replace <service-name> with the name of the desired AWS service (for example, “s3” for Amazon Simple Storage service (Amazon S3) or “ec2” for Amazon Elastic Compute Cloud (Amazon EC2)). This URL endpoint provides a JSON file that contains the comprehensive list of actions, resources, and condition keys that are available for that particular service.

The following example shows the format of the output from the service-list.json file, which contains the service names and URLs for each service’s reference information:

[ 
    {
"service": "s3", 
        "url": "https://servicereference.us-east-1.amazonaws.com/v1/s3/s3.json" 
    }, 
    {
"service": "dynamodb", 
        "url": "https://servicereference.us-east-1.amazonaws.com/v1/dynamodb/dynamodb.json" 
    }, 
    …
]

You can navigate to the service information page by using the url field to view the list of permissions for the service. You can also download the JSON file to use in your policy authoring workflows. For example, you can download the permissions for Amazon S3 by following this URL:
https://servicereference.us-east-1.amazonaws.com/v1/s3/s3.json

The following example shows a partial output of the permissions for Amazon S3. The AWS Identity and Access Management (IAM) actions are available in JSON format, and each action is its own JSON object. The Name field for those objects provides the name of the IAM action, the ActionConditionKeys field provides the available condition keys for this action, and the Resources field provides the available resources for this action.

{
  "Name" : "s3",
  "Actions" : [ {
    "Name" : "AbortMultipartUpload",
    "ActionConditionKeys" : [ "s3:AccessGrantsInstanceArn", "s3:AccessPointNetworkOrigin", "s3:DataAccessPointAccount", "s3:DataAccessPointArn", "s3:ResourceAccount", "s3:TlsVersion", "s3:authType", "s3:signatureAge", "s3:signatureversion", "s3:x-amz-content-sha256" ],
    "Resources" : [ {
      "Name" : "object"
    } ]
  }, {
    "Name" : "AssociateAccessGrantsIdentityCenter",
    "ActionConditionKeys" : [ "aws:ResourceTag/${TagKey}", "s3:ResourceAccount", "s3:TlsVersion", "s3:authType", "s3:signatureAge", "s3:signatureversion", "s3:x-amz-content-sha256" ],
    "Resources" : [ {
      "Name" : "accessgrantsinstance"
    } ],
    "Version": "v1.1" 
}

What can you build with the service reference information?

Let’s explore how you can make use of the service reference information through practical examples. To help you get started, here are two custom tools that use the service reference information. You can find these tools in our GitHub repository, ready for you to use and adapt to your specific needs. You can download the source code for these tools by visiting the following links:

SCP pre-processor

The SCP pre-processor provides a convenient way to write SCPs. You run the SCP pre-processor as a command-line tool. The tool takes a single, monolithic JSON file and runs a series of transformations and optimizations, then outputs a collection of valid service control policies that fit within policy size quotas. The tool uses AWS service reference information data in order to optimize lists of IAM actions.

Notification tool for new or removed IAM actions

You might find yourself needing to update various policies throughout your AWS environment when new IAM actions or services are released. You can use this tool to notify you when new services or new actions are added or removed. It works by downloading the service reference information and comparing it to the previous version of the file when the tool last ran. You can use these notifications to perform actions like automatically updating IAM policies when new actions are added or manually reviewing the notifications for new, sensitive actions.

Visit the source code repositories for the SCP pre-processor and the daily notification tool to learn more.

Conclusion

The AWS service reference information makes it easier for you to create automation for policy authoring and validation. By providing the AWS service actions reference in JSON format, this feature enables you to create custom tools for policy authoring and management.

We’re excited to know what kind of policy authoring tools you can think up.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Ramesh Rajan
Ramesh Rajan

Ramesh is a Senior Solutions Architect based out of San Francisco. He holds a Bachelor of Science in Applied Sciences and a Master’s in Cyber Security and Information Assurance. He specializes in cloud migration, cloud security, compliance, and risk management.
Matt Luttrell
Matt Luttrell

Matt is a Principal Solutions Architect on the AWS Identity Solutions team. When he’s not spending time chasing his kids around, he enjoys skiing, cycling, and the occasional video game.

Master architecture decision records (ADRs): Best practices for effective decision-making

Post Syndicated from Christoph Kappey original https://aws.amazon.com/blogs/architecture/master-architecture-decision-records-adrs-best-practices-for-effective-decision-making/

Architecture decision records (ADRs) help you document and communicate important process and architecture decisions in your engineering projects. Based on our experience implementing over 200 ADRs across multiple projects, we’ve developed best practices that can help you streamline your decision-making processes and improve team collaboration.

In this post, you’ll learn:

  • How to implement ADRs in your organization
  • Best practices based on more than 200 ADRs across multiple projects
  • Practical tips for streamlining architectural decision-making
  • Real-world examples from projects with 10 to more than 100 team members

Common challenges in architecture decision-making

Before implementing ADRs, your teams might face these common challenges:

  1. Team alignment – Development teams spend a huge part of their time (20 –30%, based on our project experience of the past 3 years) coordinating with other teams, which can slow down feature deployment and increase costs through repeated architecture refactoring
  2. Design flexibility – Finding the right balance between upfront design and evolving architecture when working with agile and DevOps approaches
  3. Nonfunctional requirements – Making trade-offs between security, maintainability, and scalability requirements
  4. Changing requirements – Adapting architectural decisions to evolving business goals while maintaining system integrity
  5. Knowledge transfer – Onboard new team members efficiently and make sure they follow the team’s current way of working

How to streamline the decision-making process

We base the recommendations in this post on our experience with several projects, working with teams with fewer than 10 team members as well as complex projects with 100 team members across 10 work streams. We embarked on ambitious projects with a green-field start as well as projects covering ongoing development of new features in production. Especially in teams with 100 people contributing to the code base, we faced the challenge of making sure that collaboration was seamless and decision-making consistent.

To address this challenge, we implemented an ADR mechanism, which served as our guiding light throughout the project’s lifecycle. After more than 3 years of following this approach, we’ve amassed a wealth of experience and best practices that we’re excited to share with the software development community. By capturing the context, alternatives considered, and the rationale behind each decision, ADRs foster transparency, knowledge-sharing, and accountability within teams. Our goal is to guide you through the process of writing effective ADRs with the following best practice recommendations:

  1. Keep ADR meetings short and focused – Effective ADR meetings should be concise and time-bound. Aim to keep them 30–45 minutes maximum. This focused approach keeps discussions on track and participants engaged throughout the process.
  2. Embrace the readout meeting style – Adopt the readout meeting style, where participants spend 10–15 minutes reading the ADR document. Encourage attendees to provide written comments on sections, paragraphs, or sentences that require clarification or where they have differing opinions. This approach promotes active engagement and fosters a bias for action and frugality.
  3. Maintain a cross-functional yet lean participant list – Invite representatives from each team that might be affected by the architectural decision but strive to keep the total number of participants below 10. This cross-functional representation provides diverse perspectives while maintaining a lean and efficient decision-making process, aligning with the principles of frugality and bias for action.
  4. Focus on a single decision – Keep ADRs concise by focusing on a single decision. Don’t hesitate to split up decisions if necessary. Concentrating on one decision at a time simplifies the decision-making process so that participants can thoroughly evaluate the impact during readout sessions. This approach aligns with the principles of ownership and customer obsession.
  5. Separate design from decision – Use a separate design document mechanism to explore alternative options thoroughly. Reference these design documents within the ADR, adhering to the principles of invention and simplification.
  6. Address comments and resolve feedback – Actively follow up on comments received during the ADR review process. Resolve all comments, either by incorporating changes or by discussing and reaching a consensus with the comment author. This practice demonstrates a commitment to delivering results and fostering a sense of ownership.
  7. Push for a timely decision – Avoid prolonged discussions and multiple readout meetings. Based on our experience, one to three ADR readouts should be sufficient. If more sessions are required, reevaluate the dependencies and consider reducing the number of invitees or reducing the scope of the ADR. Most of the decisions are two-way door decisions, meaning that they can be changed with little impact in the future. It’s always better to make a decision and try it fast instead of endlessly discussing it. This approach aligns with the AWS principles of working backwards, customer obsession, delivering results, and being right a lot.
  8. Embrace team collaboration – Approving an ADR is a team effort. The author must own the document and gather feedback from all affected teams before finalizing the decision. This practice encourages having backbone, disagreeing and committing, and fostering a collaborative environment.
  9. Maintain and follow the process – Keep ADRs up to date and follow the established process. If an ADR supersedes a previous one, document the change and link the new ADR in the superseded document. Insist on the highest standards by adhering to the defined processes—consider ADRs as a team law.
  10. Centralize ADR storage – Store ADRs in a central location accessible to all project members, regardless of their team affiliation. This practice promotes transparency and makes sure that architectural decisions are readily available to everyone involved.

Implementation tips and success measures

When implementing these practices, we recommend that you start small with a pilot team, create clear templates, and establish review cycles. Defining success measures such as the time to decision, team satisfaction, architecture rework reduction, or cross-team collaboration improvement help to evaluate your decision-making process

Conclusion

By implementing these best practices for ADRs, you’ll streamline your decision-making processes, foster collaboration, and make sure that architectural decisions are well-documented, communicated, and aligned with your organization’s principles and goals. Embrace these practices and witness the positive impact they have on the success of your software projects.

Read the AWS Prescriptive Guidance for an introduction into ADRs and an example ADR or the homepage of ADR GitHub organization.


About the Authors

Visually build telephony applications with AWS Step Functions

Post Syndicated from Reynaldo Hidalgo original https://aws.amazon.com/blogs/messaging-and-targeting/visually-build-telephony-applications-with-aws-step-functions/

Developers face numerous challenges when building telephony applications: managing unpredictable user responses, handling disconnections, processing incorrect inputs, and addressing errors. These challenges extend development cycles and create unstable applications that fail to meet user expectations.

This blog demonstrates how Amazon Web Services (AWS) Step Functions, combined with Amazon Chime SDK Public Switched Telephone Network (PSTN) audio service, offers a solution to overcome these challenges.

Overview of the solution

To demonstrate our solution, we built a sample telephony application that lets business owners manage customer calls through a dedicated business phone number. This solution helps small business owners separate personal and business communications, while managing all calls from their existing phone.

The beta version of this sample application delivers these six core call flows:

  1. During business hours: Routes incoming customer calls to the business owner
  2. After hours: Enables customers to leave voice messages
  3. Message retrieval: Allows owner to access customer voice messages
  4. Business caller ID: Enables owner to call customers using the business number
  5. Call scheduling: Permits owner to schedule customer calls for later in the day
  6. Automated calling: Initiates scheduled calls between owner and customer automatically

Using Workflow Studio, we built a Step Functions workflow (Figure 1) that processes all six call flows and handles unexpected scenarios.

Figure 1 – Visual diagram of a telephony workflow created in Workflow Studio for Step Functions, showing six interconnected call routing paths with decision points and error handling states. Each path represents a different customer interaction scenario, connected by arrows indicating the flow direction.

Figure 1 – Step Functions telephony workflow designed in Workflow Studio

How it works

AWS Step Functions enable agile visual workflow design, through pre-built components and error handling rules. This creates workflows composed of event-driven states that input, process, and output JavaScript Object Notation (JSON)-formatted messages. The PSTN audio service streamlines telephony applications through its serverless approach using a request/response programming model. It invokes AWS Lambda functions with Events and waits for Actions responses, both in predefined JSON formats. This shared JSON format enables seamless integration between the PSTN audio service and Step Functions, leading us to design a serverless architecture (Figure 2) that allows for bidirectional JSON message exchange between the two services.

Figure 2 – Architectural diagram showing the integration flow between AWS Step Functions and PSTN audio service. Arrows indicate JSON message exchange between services, with Lambda functions handling the communication. The diagram illustrates the serverless architecture components and their connections in a top-to-bottom layout.

Figure 2 – Serverless architecture for Step Functions and PSTN audio service integration

Main components:

  • eventRouter: Lambda function managing JSON message exchange
  • appWorkflow: Step Functions implementing call flow logic
  • actionsQueue: Amazon Simple Queue Service (Amazon SQS) queue storing response actions

Architecture flow:

  1. PSTN audio service receives inbound call
  2. Service sends NEW_INBOUND_CALL event to eventRouter
  3. eventRouter creates the actionsQueue
  4. eventRouter asynchronously executes appWorkflow with event data
  5. eventRouter begins long-polling from actionsQueue, waiting for next action(s) message
  6. appWorkflow processes JSON-formatted event data, computing next action(s)
  7. appWorkflow queues next action(s) using Amazon SQS SendMessage API with Wait for Callback with Task Token integration pattern to stop the workflow until the next event call is received
  8. eventRouter retrieves and removes action(s) from actionsQueue
  9. eventRouter returns action(s) to PSTN audio service

Observations:

  • eventRouter code logic is generic and agnostic from the calls and different Step Function workflows
  • eventRouter queries an environment variable to determine the workflow to call
  • Pairs of actionsQueue and appWorkflow instances lives for the duration of each call
  • eventRouter is responsible for the creation and deletion of each actionsQueue
  • appWorkflow instances are created by the eventRouter at the start of each call
  • appWorkflow instances complete its execution when all parties involved on the call hang up

Building your telephony application

Prerequisites:

Implementation Guidelines:

  • Create dedicated Step Functions workflows for each telephony application
  • Design and implement workflows using Workflow Studio
  • Use a Standard workflow type to accommodate extended call durations
  • Update the eventRouter Lambda function’s “CallFlowsDIDMap” environment variable to map phone numbers to their workflow Amazon Resource Name (ARN)
  • Set workflow variables in the “Init” state Variables tab (Figure 3). The eventRouter function automatically sets “QueueUrl”, and adding other variables here removes the need for external storage
Figure 3 – Screenshot of Workflow Studio's Variables tab showing an editable text box for JSON data entry. The interface displays a code editor with syntax highlighting for entering variable names and their values that persist throughout the workflow execution.

Figure 3 – Step Functions “Init” state Variables tab showing workflow data configuration

  • Configure Choice state rules to route calls based on conditions. Rules one through three (Figure 4) handle call routing based on inbound/outbound direction, owner/customer identification, while the default rule manages unexpected scenarios.
Figure 4 – Screenshot of Workflow Studio's Choice state configuration panel. The interface shows a rules editor where multiple condition blocks are displayed. Each block contains dropdown menus and input fields for setting call routing logic based on variable values. The rules appear in a vertical list with options to add, edit, or remove conditions.

Figure 4 – Step Functions Choice state defines rules for call routing decisions

  • Configure the SQS: SendMessage state (Figure 5) to instruct the next action to the PSTN audio service by:
    • Formatting the message content to match supported actions for the PSTN audio service
    • Setting TransactionAttributes to pass back and forth the values of the “WaitToken” and “QueueUrl” throughout the call duration
    • Enabling the Wait for Callback with a Task Token integration pattern
Figure 5 – Screenshot of the SQS: SendMessage state configuration in Step Functions Workflow Studio. The interface shows three main concepts: a message content formatter for PSTN audio service actions, transaction attribute fields for the WaitToken and QueueUrl values, and callback integration pattern settings. The message content input section displays input fields and options for setting up the message structure that enables communication between Step Functions and the PSTN audio service.

Figure 5 – SQS: SendMessage state configuration for PSTN audio service callback integration

  • Leverage AWS service integration states to interact with other AWS services directly from the workflow.
    • Example: Use a DynamoDB PutItem state (Figure 6) to store Amazon Simple Storage Service (Amazon S3) recording files, including bucket name and key, in Amazon DynamoDB.
Figure 6 – Screenshot of Step Functions Workflow Studio showing a DynamoDB PutItem state configuration. The interface displays fields for setting up direct interaction with DynamoDB to store S3 recording file information. The configuration panel includes input parameters for the DynamoDB table, item details, and S3 bucket and key values.

Figure 6 – AWS service integration states enable direct service connections without custom code

  • Utilize JSONata expressions (Figure 7) to minimize the number of Lambda functions.
    • Example: For Amazon EventBridge scheduling, compute time expressions using JSONata functions [$fromMillis(), $millis(), number()] and string concatenation to handle customer call scheduling.
Figure 7 – Screenshot of Step Functions Workflow Studio showing JSONata expression configuration. The interface displays a code editor with syntax highlighting where time calculation expressions are written using JSONata functions like $fromMillis(), $millis(), and number(). The panel demonstrates how to transform data directly within the workflow, eliminating the need for separate Lambda functions. Example expressions show date and time calculations for EventBridge scheduling.

Figure 7 – JSONata expressions for direct data transformation without Lambda functions

  • Use Step Functions error handling with success and fail states (Figure 8) to manage error paths and call termination results.
Figure 8 – Screenshot of Step Functions Workflow Studio showing the error handling configuration interface. The panel displays multiple state configurations: error catching paths for failed calls, success state definitions for completed calls, and termination handling settings. The interface includes dropdown menus and input fields for defining error types, retry attempts, and fallback actions. Visual connections between states illustrate the error handling flow from detection through resolution.

Figure 8 – Call error handling and termination setup

Key benefits

This approach for building telephony applications offers multiple advantages:

  1. Visual workflow-based designer
  2. Self-document call flow logic
  3. Managed versioning and publishing
  4. Native integration with AWS Services
  5. Visual log and inspection for each call
  6. Auto-scalable
  7. Pay-per-use pricing

Deploying the solution

 The following steps allows you to deploy the sample telephony application together with the serverless architecture (Figure 2).

 Prerequisites:

  1. AWS Management Console access
  2. Node.js and npm installed
  3. AWS Command Line Interface (AWS CLI) installed and configured

 Walkthrough:

The Cloud Development Kit (CDK) project on the AWS GitHub repository will deploy the following resources:

  • phoneNumberBusiness – Provisioned phone number for the sample application
  • sipMediaApp – SIP media application that routes calls to lambdaProcessPSTNAudioServiceCalls
  • sipRule – SIP rule that directs calls from phoneNumberBusiness to sipMediaApp.
  • stepfunctionBusinessProxyWorkflow – Step Functions workflow for the sample application
  • roleStepfuntionBusinessProxyWorkflow – IAM Role for stepfunctionBusinessProxyWorkflow
  • lambdaProcessPSTNAudioServiceCalls – Lambda function for call processing
  • roleLambdaProcessPSTNAudioServiceCalls – IAM Role for lambdaProcessPSTNAudioServiceCalls
  • dynamoDBTableBusinessVoicemails – DynamoDB table to store customer voicemails
  • s3BucketApp –S3 bucket for storing system recordings and customer voicemails
  • s3BucketPolicy – IAM Policy granting PSTN audio service access to s3BucketApp
  • lambdaOutboundCall – Lambda function for placing scheduled customer calls
  • roleLambdaOutboundCall – IAM Role for lambdaOutboundCall
  • roleEventBridgeLambdaCall – IAM Role to allow the EventBridge service to execute lambdaOutboundCall

Follow these steps to deploy the CDK stack:

  1. Clone the repository
git clone https://github.com/aws-samples/amazon-chime-sdk-visual-media-applications 

cd amazon-chime-sdk-visual-media-applications 

npm install
  1. Bootstrap the stack
#default AWS CLI credentials are used, otherwise use the –-profile parameter
#provide the <account-id> and <region> to deploy this stack 
cdk bootstrap aws://<account-id>/<region>
  1. Deploy the stack
#default AWS CLI credentials are used, otherwise use the –-profile parameter
#personalNumber: the personal phone number of the business owner in E.164 format 
#businessAreaCode: the United States area code used to provision the business number 
cdk deploy –-context personalNumber=+1NPAXXXXXXX –-context businessAreaCode=NPA

Call the provisioned phone number to test the sample application. Optionally, edit the workflow to update the business name and working hours on the “Init” Task state, in the Variables tab.

Cleaning up:

To clean up this demo, execute:

cdk destroy

Conclusion

This blog demonstrates how combining AWS Step Functions and Amazon Chime SDK PSTN audio service streamlines the development of reliable telephony applications through visual workflow design and managed error handling. We provided a sample application, implementing six core business phone features, showcasing how the solution effectively manages multiple conditional paths and edge cases like disconnections and invalid inputs.

The serverless architecture created enables seamless integration between the two services through JSON-based communication, while providing automatic scaling and pay-per-use pricing. Together, these components create a robust foundation for building sophisticated telephony applications that reduce maintenance costs and enhance reliability.

Contact an AWS Representative to know how we can help accelerate your business.

AWS KMS CloudWatch metrics help you better track and understand how your KMS keys are being used

Post Syndicated from Norman Li original https://aws.amazon.com/blogs/security/aws-kms-cloudwatch-metrics-help-you-better-track-and-understand-how-your-kms-keys-are-being-used/

AWS Key Management Service (AWS KMS) is pleased to launch key-level filtering for AWS KMS API usage in Amazon CloudWatch metrics, providing enhanced visibility to help customers improve their operational efficiency and aid in security and compliance risk management.

AWS KMS currently publishes account-level AWS KMS API usage metrics to Amazon CloudWatch, enabling you to monitor and manage your API usage. However, if you’re using numerous KMS keys, pinpointing the ones with the highest request rate quota usage or significant API costs becomes challenging. For example, if you have more than 10 active KMS keys in your account, prior to this launch you would have needed to build a custom CloudTrail and Amazon Athena based solution to locate which specific keys are driving the majority of API usage and costs. With the new CloudWatch metrics, which are available under the AWS/KMS namespace in CloudWatch, you can track, understand, and set alerts on detailed API usage at the individual KMS key level without building a costly customized solution.

This blog post explores several use cases to help you better take advantage of these newly introduced CloudWatch metrics to manage your AWS KMS API usage and costs. The use cases cover viewing and understanding your API usage at the key level, and creating CloudWatch alerts to detect unintentional runaway usage.

Overview of new CloudWatch metrics for KMS keys

With CloudWatch metrics for KMS keys, you can now do the following:

  1. View the API usage for a specific KMS key, filtered by individual API operations (for example, Encrypt, Decrypt, or GenerateDataKey).
  2. See the aggregated usage across cryptographic operations for a given KMS key.
  3. Set up an alarm if a specific KMS key exceeds a specified threshold on a single API operation, or a set of API operations.

This streamlined approach allows you to quickly monitor, understand, and troubleshoot the API usage patterns of your KMS keys, without the overhead of the previous multi-step process. Let’s detail how these key-level API usage metrics can be used in two real-world examples.

Example 1: How to locate the KMS keys that consume the most API usage quota or contribute the most API charges

When you surpass your AWS KMS API request rate quotas, you can view your AWS KMS API utilization within the Service Quotas console. However, you might still find it cumbersome to identify the KMS keys that consume the largest amount of your request quota. When you receive the AWS KMS API charges that exceed your expectation, you can check the detailed billing usage in each AWS Region in Cost Explorer, but you cannot easily locate the KMS keys with the most API charges. This process becomes even more challenging when you manage a large number of KMS keys.

With the key-level API usage CloudWatch metrics, you can use the advanced metric query option to query CloudWatch Metrics Insights data with a user-friendly dialect of SQL to locate the KMS keys that consume the largest portion of the API usage quota or contribute the most API charges.

Walkthrough

To use Amazon CloudWatch Metrics Insights to identify the top 20 KMS keys that have the most cryptographic API usage up to the last 3 hours, complete the following steps:

  1. Open the CloudWatch console.
  2. In the navigation pane, choose Metrics, and then choose All metrics.
  3. Choose the Multi source query tab.
  4. For the data source, choose CloudWatch Metrics Insights.
  5. You can enter the following example query in Editor view:

    Note: In Builder view, the metric namespace, metric name, filter by, group by, order by, and limit options are shown. In Editor view, the same options as in Builder view are shown in query format.

    	SELECT SUM(SuccessfulRequest)
    	FROM SCHEMA("AWS/KMS", KeyArn, Operation)
    	GROUP BY KeyArn
    	ORDER BY MAX () DESC
    	LIMIT 20

  6. Choose Run in the Editor view or Graph query in the Builder view.

Example 2: How to set a new detailed alarm on unintentional runaway AWS KMS API usage

Running big data processing workflows that read Amazon Simple Storage Service (Amazon S3) files encrypted by KMS keys is a common scenario for analytics, business reporting, or machine learning projects. Typically, these workflows read a limited number of files from S3 on each invocation. However, misconfigured workflows could unintentionally read a large number of S3 files, which could result in exceeding your AWS KMS API request rate quotas or incurring undesirable charges due to spiky AWS KMS API usage. Historically, to address this issue, you would have had to build a customized alarm system by following these steps: 1) send AWS CloudTrail events generated by AWS KMS to Amazon CloudWatch Logs; 2) write queries in Amazon CloudWatch Logs Insights to track your API request usage; and 3) enable anomaly detection on the corresponding CloudWatch Log Insights math expression.

Now, with key-level API usage CloudWatch metrics, you can directly enable anomaly detection on these metrics to set up alarms for anomalous AWS KMS API usage patterns. This provides a more streamlined and efficient way to monitor and detect potential runaway workflows. By using these CloudWatch metrics and anomaly detection capabilities, you can proactively identify and address unintended increases in AWS KMS API usage, helping to avoid unexpected charges or service disruptions in your analytics, reporting, or machine learning pipelines.

Walkthrough

Consider a scenario where you have an analytics workflow that runs frequently, which uses the Decrypt AWS KMS API operation on a KMS key to decrypt and read data from S3. You would like to enable anomaly detection on the KMS key to trigger an alarm when the Decrypt call volume to the specific KMS key sees a discernible trend or pattern. To do so, complete the following steps:

  1. Open the CloudWatch console.
  2. In the navigation pane, choose Metrics, and then choose All metrics.
  3. Choose KMS, and then choose KeyArn, Operation.
  4. In the search bar, enter the Amazon Resource Name (ARN) of the key, and then choose Search. Select the CloudWatch metric you would like to enable anomaly detection for.
  5. Navigate to Graphed metrics, and using the Statistic and Period drop-down lists, choose the statistic and period that you would like to monitor. Then you can enable anomaly detection by selecting the Pulse icon.

    Figure 1: How to enable anomaly detection on a SuccessfulRequest metric

    Figure 1: How to enable anomaly detection on a SuccessfulRequest metric

  6. You can adjust the anomaly detection by setting the sensitivity to adjust the bandwidth, if needed.

    Figure 2: Anomaly detection is enabled on the SuccessfulRequest metric. The gray band illustrates the expected range of values and the anomaly is in red

    Figure 2: Anomaly detection is enabled on the SuccessfulRequest metric. The gray band illustrates the expected range of values and the anomaly is in red

Conclusion

This blog post highlighted the newly introduced key-level filtering capability for the AWS KMS API usage in CloudWatch. We showed two real-world use cases to demonstrate how you can use the new CloudWatch metrics. These use cases include improving operational visibility, setting up proactive alarms on anomalies in KMS API usage patterns, and potentially tracking detailed key usage for compliance purposes.

If you have feedback about this blog post, submit comments in the Comments section below. If you have questions about this blog post, start a new thread in the AWS Key Management Service re:Post.
 

Norman Li
Norman Li

Norman is a Software Development Manager for AWS KMS. In this role, Norman leads the development of visibility features, as well as internal scalability initiatives. Outside of work, Norman likes to spend time in the beautiful Pacific Northwest mountains.
Haiyu Zhen
Haiyu Zhen

Haiyu is a Senior Software Development Engineer for AWS KMS. She specializes in building secure, large-scale distributed systems and is passionate about enhancing cloud-native application security without compromising performance.

Architect fault-tolerant applications with instance fleets on Amazon EMR on EC2

Post Syndicated from Deepmala Agarwal original https://aws.amazon.com/blogs/big-data/architect-fault-tolerant-applications-with-instance-fleets-on-amazon-emr-on-ec2/

Organizations rely on Amazon EMR on EC2 clusters to process large-scale data workloads using frameworks like Apache Spark, Apache Hive, and Trino. Events such as TV advertisements or unplanned promotions might lead to an increase in demand of compute capacity, making effective capacity planning necessary to make sure your workloads don’t hit capacity limits or job failures.

A common scenario is to run daily Spark jobs on Amazon EMR using consistent Amazon Elastic Compute Cloud (Amazon EC2) instance types (for example, a single instance size and family for the cluster). Although this might work well to sustain the baseline, spikes can trigger auto scaling, which narrows the chances of capacity availability when trying to stop and relaunch a larger EMR cluster, because the specific on-demand instance pool might lack capacity to meet the demand.

In this post, we show how to optimize capacity by analyzing EMR workloads and implementing strategies tailored to your workload patterns. We walk through assessing the historical compute usage of a workload and use a combination of strategies to reduce the likelihood of InsufficientCapacityExceptions (ICE) when Amazon EMR launches specific EC2 instance types. We implement flexible instance fleet strategies to reduce dependency on specific instance types and use Amazon EC2 On-Demand Capacity Reservation (ODCRs) for predictable, steady-state workloads. Following this approach can help prevent job failures due to capacity limits while optimizing your cluster for cost and performance.

Solution overview

Instance fleets in Amazon EMR offer a flexible and robust way to manage EC2 instances within your cluster. This feature allows you to specify target capacities for On-Demand and Spot Instances, select up to five EC2 instance types per fleet (or 30 when using the AWS Command Line Interface [AWS CLI] and API with an allocation strategy), and use multiple subnets across different Availability Zones. Importantly, instance fleets support the use of ODCRs, enabling you to align your EMR clusters with pre-purchased EC2 capacity. You can configure your instance fleet to prefer or require capacity reservations, making sure that your EMR clusters use your reserved capacity efficiently.

EMR workload patterns typically fall into two categories: stable and variable (spiky). In the following sections, we explore how to optimize for each pattern using various options available with instance fleets, starting with stable workloads and then addressing variable workloads.

Stable workloads are workloads with a predictable pattern of resource utilization over time; for example, a pharmaceutical provider needs to process 21 TB of research data, patient records, and other information daily. The workload is consistent and needs to run reliably every day on long-running persistent clusters. For critical business operations requiring high reliability and guaranteed capacity, we recommend reserving the baseline capacity as part of your capacity planning. We demonstrate the following steps:

  1. Use AWS Cost and Usage Reports (AWS CUR) to estimate the baseline of existing workloads.
  2. Reserve the baseline capacity using ODCR.
  3. Configure Amazon EMR to use the targeted ODCR.

Spiky workloads are defined by unpredictable and often significant fluctuations in processing demands. These surges can be triggered by various factors (such as batch processing, real-time data streaming, or seasonal business fluctuations) that trigger Amazon EMR to request more capacity to match the demand. We address the resource allocation by using instance and Availability Zone flexibility, with the following steps:

  1. Introduce EC2 instance flexibility with EMR instance fleets.
  2. Achieve resiliency through intelligent subnet selection with EMR instance fleets.
  3. Use managed scaling to automatically manage scaling in and out.

Stable workloads

In this section, we demonstrate how to define your baseline, configure AWS Identity and Access Management (IAM) permissions, create an ODCR, and associate your reservations to a capacity group and configure Amazon EMR to use targeted ODCRs. You can opt for a mixed ODCR strategy—for example, one ODCR with a short period of duration that supports the launch of your EMR cluster, and another ODCR with a longer period of duration that supports your task nodes based on the baseline capacity reservation.

Estimate the baseline

Make sure to activate the AWS generated cost allocation tag aws:elasticmapreduce:job-flow-id. This enables the field resource_tags_aws_elasticmapreduce_job_flow_id in the AWS CUR to be populated with the EMR cluster ID and is used by the SQL queries in the solution. To activate the cost allocation tag from the AWS Billing Console, complete the following steps:

  1. On the AWS Billing and Cost Management console, choose Cost allocation tags in the navigation pane.
  2. Under AWS generated cost allocation tags, choose the aws:elasticmapreduce:job-flow-id tag.
  3. Choose Activate.

It can take up to 24 hours for tags to activate. For more information, see here.

After the tags are activated, you can use AWS CUR and perform the following query on Amazon Athena to find the compute resources used by the EMR cluster ID vs. the timeline of usage. For more details, see Querying Cost and Usage Reports using Amazon Athena. Update the following query with your CUR table name, EMR cluster ID, desired timestamps, and AWS account ID, and run the query on Athena:

SELECT bill_payer_account_id as Payer,
    product_product_family as PFamily,
    product_product_name as PName,
    resource_tags_aws_elasticmapreduce_job_flow_id,
    line_item_usage_account_id as LinkedAccount,
    line_item_usage_start_date as UsageDate,
    bill_billing_period_start_date as BillingDate,
    SPLIT_PART(line_item_usage_type, ':', 2) AS InstanceType,
    line_item_availability_zone AS AvailabilityZone,
    COUNT(line_item_resource_id) as ResourceIDCount
FROM <YOUR_CUR_TABLE_NAME>
WHERE (
        line_item_usage_start_date BETWEEN TIMESTAMP 'YYYY-MM-DD 00:00:00'
        AND TIMESTAMP 'YYYY-MM-DD 23:59:59' 
    )
    AND line_item_operation LIKE '%%RunInstance%%'
    AND line_item_line_item_type LIKE '%%Usage%%'
    AND product_product_family NOT IN ('Data Transfer')
    AND resource_tags_aws_elasticmapreduce_job_flow_id LIKE '%%<emr-cluster-id>%%'
    AND line_item_usage_account_id IN (
        '<aws_account_id>'
)
GROUP BY 1,2,3,4,5,6,7,8,9

As an example, the preceding query filters instances usage per hour for a given account and EMR cluster for the period of 6 months, to generate the following figure. You can export the results in CSV format and analyze the data. Now that you have a visual representation of your workloads’ baseline and bursts, you can define the strategy and configuration of your EMR cluster.

Create an ODCR to reserve the baseline capacity

ODCRs can be either open or targeted:

  • With an open ODCR, new instances and existing instances that have matching attributes (such as operating system or instance type) will run using the capacity reservation attributes first.
  • With a targeted ODCR, instances must match the attributes of the ODCR specification and the ODCR is specifically targeted at launch. This approach is recommended if you have multiple concurrent EMR clusters consuming capacity from the shared On-Demand pool of EC2 instances. EMR clusters larger than the targeted ODCR quantity will fall back to On-Demand Instances that are in the same Availability Zone.

In this example, we use a targeted ODCR with an EMR instance fleet in the us-east-1a Availability Zone. The following diagram illustrates the workflow.

Complete the following steps:

  1. Use the create-capacity-reservation AWS CLI command to create the ODCR and make a note of the CapacityReservationArn value in the output:
aws ec2 create-capacity-reservation \
     --availability-zone <Input Your Availability Zone> \
     --instance-type r8g.2xlarge \
     --instance-match-criteria targeted \
     --instance-platform Linux/UNIX \
     --instance-count <enter the number of instances out of your baseline estimation>

We get the following output:

{
     "CapacityReservation": {
         "CapacityReservationId": "cr-0123456f9907xxxxx",
         "OwnerId": "XXXX",
         "CapacityReservationArn": "arn:aws:ec2:us-east-1:XXXX:capacity-reservation/cr-0123456f9907xxxxx",
         "InstanceType": "r8g.2xlarge",
         "InstancePlatform": "Linux/UNIX",
         "AvailabilityZone": "us-east-1a"

 ....
     }
 }

You can use Amazon CloudWatch to monitor ODCR usage and trigger an alert for unused capacity. For more details, see Monitor Capacity Reservations usage with CloudWatch metrics.

  1. Create a resource group named EMRSparkSteadyStateGroup and make a note of GroupArn values in the output:
aws resource-groups create-group --name EMRSparkSteadyStateGroup \
--configuration '{"Type":"AWS::EC2::CapacityReservationPool"}' '{"Type":"AWS::ResourceGroups::Generic", "Parameters":[{"Name":"allowed-resource-types","Values":["AWS::EC2::CapacityReservation"]}]}'

We get the following output:

"Group": {
         "GroupArn": "arn:aws:resource-groups:us-east-1:XXXX:group/EMRSparkSteadyStateGroup",
         "Name": "EMRSparkSteadyStateGroup"
     }, ...
  1. Use the following code to associate the capacity reservation to the resource group. You can have multiple capacity reservations associated to a resource group.
aws resource-groups group-resources --group EMRSparkSteadyStateGroup \
 --resource-arns arn:aws:ec2:us-east-1:XXXX:capacity-reservation/cr-0123456f9907xxxxx
  1. As a best practice for effective management and cleanup, Create a tag Purpose=EMR-Spark-Steady-State for the newly created ODCR and the resource group.
# Tag your Capacity Reservation
 aws ec2 create-tags \
 --resources cr-0123456f9907xxxxx \
 --tags Key=Purpose,Value=EMR-Spark-Steady-State
# Tag your Resource Group
 aws resource-groups tag \
 --arn "arn:aws:resource-groups:us-east-1:XXXX:group/EMRSparkSteadyStateGroup" --tags Purpose=EMR-Spark-Steady-State

Implement Amazon EMR with ODCR

Complete the following steps to create an EMR cluster tagged with the specific targeted ODCR:

  1. Add required permissions to the EMR service role before using capacity reservations. With these permissions, you can lock down the resource with the specific Amazon Resource Name (ARN) of the group name to be created with the following code:
{
     "Version": "2012-10-17",
     "Statement": [
         {
             "Effect": "Allow",
             "Resource": "*",
             "Action": [
                 "ec2:CreateFleet",
                 "ec2:RunInstances",
                 "ec2:CreateLaunchTemplate",
                 "ec2:CreateLaunchTemplateVersion",
                 "ec2:DeleteLaunchTemplateVersions",
                 "ec2:DescribeCapacityReservations",
                 "ec2:DescribeLaunchTemplateVersions",
                 "resource-groups:ListGroupResources"
             ]
         }
     ]
 }
  1. Configure the EMR cluster to use ODCR with instance fleets. We use the CapacityReservationOptions parameter to configure the EMR cluster, as shown in the following example:
  {
 ...
     "LaunchSpecifications": {
       "OnDemandSpecification": {
         "AllocationStrategy": "LOWEST_PRICE",
         "CapacityReservationOptions": {
           "UsageStrategy": "USE_CAPACITY_RESERVATIONS_FIRST",
           "CapacityReservationResourceGroupArn": "arn:aws:resource-groups:us-east-1:xxxxxx:group/EMRSparkSteadyStateGroup"
         }
       }
     }
   }

The following step-by-step breakdown illustrates the Amazon EMR decision-making process when prioritizing targeted capacity reservations, from core node provisioning through task node allocation:

  • Cluster provisioning initiation:
    • The user chooses to override the lowest-price allocation strategy.
    • The user specifies targeted capacity reservations in the launch request.
  • Core node provisioning:
    • Amazon EMR evaluates all EC2 instance capacity pools with targeted capacity reservations, and selects the pool with the lowest price that has sufficient capacity for all requested core nodes.
    • If no pool with targeted reservations has sufficient capacity, Amazon EMR reevaluates all specified EC2 instance capacity pools and selects the lowest-priced pool with sufficient capacity for core nodes. Available open capacity reservations are applied automatically.
  • Availability Zone selection:
    • After the core capacity is acquired, Amazon EMR locks in the Availability Zone for your cluster.
  • Primary and task node provisioning:
    • Amazon EMR evaluates EC2 instance capacity pools within that Availability Zone for primary and task fleets. First, Amazon EMR evaluates all the pools with targeted ODCRs specified in the request, ordered by lowest price by default.
    • From the ordered list, Amazon EMR launches as much capacity as possible from the unused targeted ODCRs of each instance pool until the request is fulfilled.
    • If the unused targeted ODCRs don’t fulfill the request yet, Amazon EMR continues to launch the remaining capacity into On-Demand pools, in the lowest-price order by default.

For more details about the allocation strategy, refer to Allocation strategy for instance fleets or Amazon EMR Support for Targeted ODCR.

Spiky workloads

Spiky workloads are defined by unpredictable and often significant fluctuations in processing demands, triggered by factors such as infrequent but resource-intensive periodic batch processing jobs. For example, a geographic information system processes location data from millions of users in real time to provide up-to-date traffic information, calculate routes, and suggest points of interest. User location data is constantly being generated, but the volume can spike dramatically during rush hour or special events, as illustrated in the following figure. This graph shows the number of used resources (Amazon EC2) by hour; it varies from 1 when the cluster scales in, waiting for jobs, to spikes of 1,000 nodes.

If you’re running spiky workloads with limited flexibility in instance type, family, and Availability Zone, you might face ICE errors when the available capacity can’t meet the cluster’s scaling requirements. To address this, we explore a set of best practices for EMR cluster creation to maximize availability and balance price-performance. Although spiky workloads present a unique challenge in resource management, configuring EMR instance fleets offers a powerful solution. By using diverse instance types, prioritized allocation strategies, Availability Zone flexibility, and managed scaling, organizations can create a robust, cost-effective infrastructure capable of handling unpredictable workload patterns. This configuration offers the following benefits:

  • Improved availability – By diversifying instance types and using multiple Availability Zones, the cluster mitigates insufficient capacity issues
  • Cost savings – Allocation strategies reduce costs while minimizing interruptions
  • Resilience for spiky workloads – Prioritizing instance generations provides seamless scaling under varying demands
  • Optimized performance – Managed scaling dynamically adjusts resources to meet workload demands efficiently

Introduce EC2 instance flexibility and instance fleets with a prioritized allocation strategy

Amazon EMR supports instance flexibility with instance fleet deployment. Instance fleets give you a wider variety of options and intelligence around instance provisioning. You can now provide a list of up to 30 instance types with corresponding weighted capacities and spot bid prices (including spot blocks) using the AWS CLI or AWS CloudFormation. Amazon EMR will automatically provision On-Demand and Spot capacity across these instance types when creating your cluster. This can make it more straightforward and more cost-effective to quickly obtain and maintain your desired capacity for your clusters. In August 2024, Amazon EMR introduced the prioritized allocation strategy to enhance instance flexibility with instance fleets. This feature allows you to specify priority levels for your instance types, enabling Amazon EMR to allocate capacity to the highest-priority instances first. This strategy helps improve cost savings and reduces the time required to launch clusters, even in scenarios with limited capacity. For more details, see Amazon EMR support prioritized and capacity-optimized-prioritized allocation strategies for EC2 instances. To maximize cost-efficiency and availability for spiky workloads, combine the price-performance advantages of new-generation instances with the broader availability of previous-generation instances. For workloads with strict latency requirements, fix the instance size to maintain consistent performance. This approach takes advantage of the strengths of both instance generations, providing flexibility and reliability decreasing the likelihood of capacity constraints. For On-Demand nodes, choose the prioritized allocation strategy, so the cluster tries to use newer-generation instances first. While configuring the instance fleet, arrange instances in a prioritized order reflecting price-performance and availability trade-offs, for example:

  • Primary node – m8g.12xlarge > m8g.16xlarge > m7g.12xlarge > m7g.16xlarge
  • Core node – r8g.8xlarge > r8g.12xlarge > r7g.8xlarge > r6g.16xlarge > r5.16xlarge
  • Task Node – r8g.8xlarge > r8g.12xlarge > r7g.8xlarge > r6g.16xlarge > r5.16xlarge

For Spot Instances, make sure the capacity-optimized prioritized allocation strategy is selected to reduce interruptions. See the following CloudFormation template snippet as an example:

...
       "Properties": {
         "Instances": {
          "MasterInstanceFleet": {
            "Name": "cfnMaster",
            "InstanceTypeConfigs": [
               {
                 "BidPrice": "10.50",
                 "InstanceType": "m5.xlarge",
                 "Priority": "1",
 ...
             "LaunchSpecifications": {
               "SpotSpecification": {
                 "TimeoutAction": "SWITCH_TO_ON_DEMAND",
                 "TimeoutDurationMinutes": 20,
                 "AllocationStrategy": "CAPACITY_OPTIMIZED_PRIORITIZED"
               },
               "OnDemandSpecification": {
                "AllocationStrategy": "PRIORITIZED"
               }
 ...

Select subnets with EMR instance fleets

When creating a cluster, specify multiple EC2 subnets within a virtual private cloud (VPC), each corresponding to a different Availability Zone. Amazon EMR provides multiple subnet (Availability Zone) options by employing subnet filtering at cluster launch, and selects one of the subnets that has adequate available IP addresses to successfully launch all instance fleets. If Amazon EMR can’t find a subnet with sufficient IP addresses to launch the whole cluster, it will prioritize the subnet that can at least launch the core and primary instance fleets.

Use managed scaling

Managed scaling is another powerful feature of Amazon EMR that automatically adjusts the number of instances in your cluster based on workload demands. This makes sure that your cluster scales up during periods of high demand to meet processing requirements and scales down during idle times to save costs. With managed scaling, you can set minimum and maximum scaling limits, giving you control over costs while benefiting from an optimized and efficient cluster performance.

The following workflow illustrates Amazon EMR configured with instance fleets and managed scaling.

The workflow consists of the following steps:

  1. The user defines the EMR instance configurations and instance types, along with their launch priority.
  2. The user selects subnets for the Amazon EMR configuration to provide Availability Zone flexibility.
  3. Amazon EMR calls the Amazon EC2 Fleet API to provision instances based on the allocation strategy.
  4. The EMR instance fleet is launched.
  5. The cycle is repeated for scaling operations within the launched Availability Zone, providing optimized performance and scalability.

Conclusion

In this post, we demonstrated how to optimize capacity by analyzing EMR workloads and implementing strategies tailored to your workload patterns. As you implement any of the preceding strategies, remember to continuously monitor your cluster’s performance and adjust configurations based on your specific workload patterns and business needs. With the right approach, the challenges of spiky workloads can be transformed into opportunities for optimized performance and cost savings.

To effectively manage workloads with both baseline demands and unexpected spikes, consider implementing a hybrid approach in Amazon EMR. Use ODCRs for consistent baseline capacity and configure instance fleets with a strategic mix of ODCR, On-Demand, and Spot Instances prioritizing ODCR usage.

Try these strategies with your own use case, and leave your questions in the comments.


About the Authors

Deepmala Agarwal works as an AWS Data Specialist Solutions Architect. She is passionate about helping customers build out scalable, distributed, and data-driven solutions on AWS. When not at work, Deepmala likes spending time with family, walking, listening to music, watching movies, and cooking!

Suba Palanisamy is a Senior Technical Account Manager, helping customers achieve operational excellence on AWS. Suba is passionate about all things data and analytics. She enjoys traveling with her family and playing board games.

Flavio Torres is a Principal Technical Account Manager at AWS. Flavio helps Enterprise Support customers design, deploy, and scale resilient cloud applications. Outside of work, he enjoys hiking and barbecuing.

Manage authorization within a containerized workload using Amazon Verified Permissions

Post Syndicated from Manuel Heinkel original https://aws.amazon.com/blogs/security/manage-authorization-within-a-containerized-workload-using-amazon-verified-permissions/

Containerization offers organizations significant benefits such as portability, scalability, and efficient resource utilization. However, managing access control and authorization for containerized workloads across diverse environments—from on-premises to multi-cloud setups—can be challenging.

This blog post explores four architectural patterns that use Amazon Verified Permissions for application authorization in Kubernetes environments. Verified Permissions is a scalable permissions management and fine-grained authorization service for your applications.

In this blog post, we cover the following patterns and discuss their trade-offs:

  • Calling Verified Permissions from an Amazon API Gateway API fronting your application in Kubernetes
  • Calling Verified Permissions from a Kubernetes Ingress controller component
  • Calling Verified Permissions from a sidecar container running in the same pod as the application container
  • Calling Verified Permissions from the application container

Understanding these patterns and their implications can help you implement secure and consistent authorization mechanisms across your entire infrastructure without compromising the scalability, portability, and resource efficiency of your containerized workloads.

Consistent authorization through centralized policy management

Access to application resources can be secured more effectively with a centralized and consistent approach to authorization. Especially in containerized environments with distributed architectures and shared resources, traditional access control methods, like embedding authorization logic within individual application code or relying on local access control policies, can become difficult to manage and prone to errors. This becomes even more challenging when you have a combination of on-premises and cloud setups.

A centralized authorization solution empowers developers to implement consistent access control across individual components of an application efficiently. Benefits include reduced duplicate work, an improved security posture, and lower complexity in managing and enforcing access control policies.

Verified Permissions benefits in a containerized environment

Amazon Verified Permissions provides several key benefits as an external authorization service:

  • Benefits for the platform engineering team – Centralized authorization enables platform engineering teams to implement, maintain, and govern authorization policies across the organization without requiring changes to individual applications. This aligns with modern platform engineering practices, where platform engineering teams can provide authorization as a service to application teams, promoting consistent security standards while reducing the operational burden on development teams.
  • Consistent authorization across environments – With Verified Permissions, you can define and manage access control policies in a centralized location. This makes it easier to apply consistent authorization rules across your entire infrastructure, including on-premises deployments and different cloud environments.
  • Simplified application development – Externalizing authorization logic from applications reduces development complexity. Developers can focus on core application functionality without having to implement and maintain authorization mechanisms within each service or component. This separation of concerns promotes code modularity, reusability, and faster iteration cycles.
  • Scalable and highly available – Verified Permissions is a managed service, designed to be scalable and highly available out of the box. As your containerized workloads grow in scale and complexity, Verified Permissions can handle increasing authorization request volumes while maintaining performance and availability.
  • Fine-grained access control – Verified Permissions supports attribute-based access control (ABAC) and role-based access control (RBAC). This allows you to define granular policies in the open source Cedar language based on various attributes like user roles, resource properties, environmental factors, and more.

Integration patterns for authorization

Kubernetes provides many options for architecting applications. Therefore, there are multiple locations in a typical architecture where authorization decisions can be enforced, as shown in Figure 1.

Figure 1: Integration points for authorization in containerized workloads

Figure 1: Integration points for authorization in containerized workloads

The workflow is as follows:

  1. API Gateway. Organizations can use entry points to the application outside of the Kubernetes cluster, such as an API gateway, to obtain an authorization decision. In AWS, Amazon API Gateway enables customers to use authorizer Lambda functions to send an authorization request to Verified Permissions.
  2. Ingress controller. The Kubernetes API defines Ingress objects, which provide load balancing and routing functions on layer 7. Common Ingress controllers like Traefik offer the option to integrate external authorization services.
  3. Sidecar proxy container. You can intercept every request routed to the application by using a sidecar container running in the same pod as the application container. This sidecar container calls Verified Permissions for authorization decisions.
  4. Application container. Developers can use the Amazon SDK to communicate with Verified Permissions from inside the application when an authorization decision is needed.

In the following sections, we explore each of these patterns in detail, examining their implementation, use cases, and specific considerations. At the end of our discussion, we provide a comprehensive comparison table to help you choose the most appropriate pattern based on factors such as scalability, performance, maintenance overhead, and specific use case requirements. This will help you make an informed decision about which pattern best suits your application’s needs.

Authorization workflow

Independent of which of the four mentioned options for authorization you choose, the overall authorization workflow, shown in Figure 2, will stay the same.

Figure 2: Authorization workflow with Amazon Verified Permissions

Figure 2: Authorization workflow with Amazon Verified Permissions

The workflow is as follows:

  1. Authentication. The user first authenticates with an identity provider to obtain a JSON Web Token (JWT). You can configure the identity provider to write relevant information like user roles, tenant ID, or other needed user attributes into the JWT. You can then use this information later to make an authorization decision.
  2. API request. The user makes a request to your application that includes the JWT.
  3. Authorization information. Your application extracts the relevant information that is needed to make an authorization decision from the request. This can include principal information from the JWT, information about the resource that the user requests, and what action the user wants to perform.
  4. (Optional) Policy information point lookup. Depending on your policies, you might need additional information in order for Verified Permissions to make an authorization decision. For example, you can query ownership details for a document from a database.
  5. Authorization decision. You then send the relevant information to Verified Permissions, which returns a decision stating whether the request is permitted or forbidden.
  6. Authorization enforcement. You then enforce the decision from Verified Permissions in your application by allowing or denying an action. For a REST API, this would result in sending back an HTTP 403 forbidden status if the request was denied, or processing the request if it was allowed and sending an HTTP 200 OK status.

Authorization outside of the cluster by using Amazon API Gateway

In this pattern, authorization decisions are made at the API gateway layer before requests reach the Kubernetes cluster. When a request arrives at the API gateway, it triggers an authorization check with Verified Permissions to evaluate the request against defined policies. Based on the Verified Permissions response, the gateway either forwards the request to the containerized application or denies access.

This pattern excels in scenarios where you need coarse-grained access control that can be enforced with information accessible at the API level (such as an HTTP header or ID or access token) and that supports RBAC and ABAC. Consider a document management application where different users have access to different documents based on group membership or identity attribute.

This approach to authorization works consistently regardless of whether your application runs in containers, virtual machines, or serverless environments. The API gateway acts as a unified control point for enforcing access policies across backend services.

For implementations that use Amazon API Gateway specifically, you can use Lambda authorizers to integrate with Verified Permissions. For each incoming API request, API Gateway invokes the authorizer Lambda function, which makes a call to Verified Permissions to evaluate the request against the defined authorization policies, as shown in Figure 3.

Figure 3: Integration of Amazon Verified Permissions in Amazon API Gateway

Figure 3: Integration of Amazon Verified Permissions in Amazon API Gateway

AWS provides a quick-start solution that demonstrates this integration by using Amazon API Gateway and Amazon Cognito, making it easier to implement this pattern. The setup process is detailed in the blog post Authorize API Gateway APIs using Amazon Verified Permissions and Amazon Cognito or bring your own identity provider.

Authorization in a Kubernetes Ingress

Another option to implement coarse-grained access control in use cases as described in the previous section is to use a Kubernetes Ingress layer. Some customers prefer Kubernetes-native solutions, especially if they need to run Kubernetes clusters within and outside of AWS.

Kubernetes provides an API to create and maintain Ingress objects, operating at layer 7 (the application layer), which enables routing decisions based on HTTP attributes. This layer 7 capability makes Ingress controllers ideal for implementing authorization checks.

One Kubernetes Ingress controller that supports external authorization is Traefik Proxy. With this feature, you can delegate authorization decisions to an external service like Verified Permissions before routing requests to the application container.

Assuming that the authorization endpoint is backed by a service in the same Kubernetes cluster, the architecture looks as shown in Figure 4.

Figure 4: Integration of Amazon Verified Permissions in a Kubernetes Ingress

Figure 4: Integration of Amazon Verified Permissions in a Kubernetes Ingress

The workflow is as follows:

  1. Authenticated users access the service through an Elastic Load Balancer of type Network Load Balancer (NLB).
  2. The NLB—operating at layer 4—exposes a Kubernetes Ingress inside the cluster that provides layer 7 capabilities. The Ingress object is implemented by an Ingress controller that supports external authorization, as described earlier.
  3. The Ingress forwards the request—or parts of it—that needs authorization to a local authorization service in the cluster. We use a dedicated authorization service in this architecture because the Ingress backend service allows an external endpoint to be called for authorization.
  4. The authorization service is deployed into its own Kubernetes namespace with a dedicated Kubernetes service account. EKS Pod Identity provides the ability to link the service account in this namespace to an AWS Identity and Access Management (IAM) role that grants access to Verified Permissions by injecting temporary AWS access credentials into the pod at runtime.
  5. The authorization service extracts relevant information from the request and sends it to Verified Permissions for an authorization decision.
  6. The Ingress for the backend service awaits the response of the authorization service and forwards it to the backend service, if access is granted. The Ingress expects the authorization service to respond with HTTP status code 200 for authorized requests. If the Ingress receives HTTP status code 403, the requester is not allowed to access the requested resource, and the Ingress will block the request at this stage.
  7. Only authorized requests are forwarded to registered backend pods.

Because integration with external authorization services is not part of the Kubernetes Ingress API, you need to consult the documentation of the Ingress controller that you decide to use to determine the availability of this feature and its implementation details. Forward authentication of the Traefik Kubernetes Ingress supports this pattern and can be configured with the vendor-specific annotations described in the Traefik documentation.

Authorization in sidecar containers

Not all Ingress controllers support integration with an external authorization service. Amazon Elastic Kubernetes Service (Amazon EKS) customers might prefer the AWS Load Balancer Controller to manage the lifecycle of NLBs and ALBs for their services. Customers can continue using their existing Ingress controller, even if it does not support calling external authorization services today. You can move the authorization of requests behind the Ingress layer with the sidecar container pattern.

Sidecar containers are a common pattern for extending an application’s functionality in Kubernetes. A sidecar is a container running in the same pod as the application it relates to. This means that the sidecar and application follow the same lifecycle and share resources, such as the network ID. This pattern is a good fit when the authorization logic is service-specific. Because the authorization service is deployed alongside the application, this pattern also provides better support in situations where changes to the application demand changes in the authorization logic.

Consider a document management system where access control depends on document metadata and team structures. When a user attempts to edit a document, the sidecar queries the document’s metadata, such as the classification level, tags, and department ownership. The sidecar can also check the organizational team hierarchy to understand reporting relationships and access privileges. This context enables fine-grained authorization decisions that consider not just who the user is, but also, for example, their organizational context or the individual document’s metadata.

Although it’s possible to configure sidecar proxies such as Envoy for individual pods manually, the more convenient option is to introduce a service mesh. A service mesh provides a control plane to manage proxies, including centralized configuration, automated injection of sidecars, and an Ingress layer for traffic routing. Istio is a popular option for a service mesh in Kubernetes.

The diagram in Figure 5 shows the deployment architecture to implement authorization with Verified Permissions in a service mesh.

Figure 5: Integration of Amazon Verified Permissions in a Kubernetes Ingress

Figure 5: Integration of Amazon Verified Permissions in a Kubernetes Ingress

The workflow is as follows:

  1. Authenticated users access the application through an NLB.
  2. The request is routed through an Ingress in the Kubernetes cluster.
  3. The Ingress forwards the request directly to the backend service.
  4. Pods of the backend service consist of multiple containers. Each request is routed through an Envoy proxy first.
  5. The Envoy proxy forwards the request to a co-located container running the authorization service.
  6. Pod Identity is used to map an IAM role to a Kubernetes service account bound to the pod, which enables the authorization sidecar to invoke Verified Permissions for an authorization decision. Note that each container in this pod has access to the IAM credentials that are mapped to the service account.
  7. The Envoy proxy awaits the response of the authorization sidecar and blocks or forwards the request to the backend container, depending on the Verified Permissions authorization decision.

When Istio is deployed into a Kubernetes cluster, it introduces Custom Resource Definitions (CRDs) for managing the service mesh. The authorization workflow can be implemented using the ServiceEntry CRD and an Istio Authorization Policy. The authorization service running as a local container in the application pod becomes a registered service entry in the mesh. This service entry can then be configured in an authorization policy as the target for request authorization in the proxy. For more details, see the External Authorization section in the Istio documentation.

Application container

When it comes to integrating Verified Permissions directly within your application container, you have the advantage of fine-grained control over authorization decisions at the application level. This approach allows for more context-aware authorization checks and can be useful when you need to make authorization decisions based on application-specific data that you can query from a policy information point.

Unlike the sidecar pattern, where authorization happens before the request reaches your application code, this approach lets you gather the necessary context from your application state, databases, or other services before making the authorization call. This is particularly valuable when the authorization logic is deeply intertwined with business logic or requires data that’s only available within the application context. This pattern also supports minimizing the number of authorization requests, if, for example, only a subset of requests processed by a monolithic service require authorization.

However, it’s important to note that this tight coupling between authorization and business logic makes the system more brittle and susceptible to breakage when functional or business logic changes occur. This means that modifications to your application code might require careful consideration of their impact on the authorization logic, potentially increasing maintenance complexity.

The architecture for authorization requests from the application container is shown in Figure 6.

Figure 6: Integration of Amazon Verified Permissions in the application container

Figure 6: Integration of Amazon Verified Permissions in the application container

The workflow is as follows:

  1. Authenticated users access the application through an Elastic Load Balancer—either Application Load Balancer (ALB) or NLB depending on workload requirements.
  2. The Kubernetes service or Ingress for the backend application is directly registered at the ALB or NLB by the AWS Load Balancer Controller.
  3. Requests are directly routed to a pod that is backing the service.
  4. The backend application’s logic is responsible for identifying whether a request needs authorization. The backend uses an IAM role injected at runtime through Pod Identity, when an authorization decision from Verified Permission is needed. The backend application returns HTTP status code 403 if the decision is a deny; otherwise it will continue processing the request.

See the Simplify fine-grained authorization with Amazon Verified Permissions and Amazon Cognito blog post for details on calling Verified Permissions within an application.

Choosing the right pattern for your app

You now have a set of patterns to introduce authorization into your containerized workloads. You need to consider multiple factors and understand the trade-offs that come with each pattern to identify the best option for a given scenario. In the following table, we list certain areas with influence on your architectural decisions.

Granularity of authorization decisions
API gateway
  • Authorization on API or service level
  • Decision based on information from HTTP request
  • Suitable for consistent coarse-grained authorization
Ingress controller
  • Authorization on API or service level
  • Decision based on information from HTTP request
  • Suitable for consistent coarse-grained authorization
Sidecar proxy
  • Authorization on service level
  • Decision based on information from HTTP request and service domain (such as policy information point or static service-specific rules)
  • Suitable for service-specific authorization with low or mid-level complexity for decisions
Application container
  • Authorization on code level
  • Decision based on information from HTTP request and arbitrary business logic
  • Suitable for highly complex decision logic
Resource overhead
API gateway
  • No cluster resources needed for authorization
  • Unauthorized requests don’t consume cluster resources
Ingress controller
  • Central Ingress pods consume cluster resources
  • Unauthorized requests don’t consume application pod resources
Sidecar proxy
  • Authorization services increases resource demand of each pod in the cluster
  • Unauthorized requests consume application pod resources
Application container
  • Authorization service consumes resources only when authorization is performed
  • Unauthorized requests consume CPU cycles of application logic until the authorization logic is triggered
Scalability
API gateway
  • Fully managed serverless service
Ingress controller
  • Scaling of Ingress pods needs to be defined
  • Cluster auto-scaling or capacity planning for compute resources in cluster needed
Sidecar proxy
  • Existing scaling policies can be leveraged
Application container
  • Existing scaling policies can be leveraged
Performance
API gateway
  • Invokes Verified Permission in AWS for each request that needs authorization
  • Supports caching to reduce number of requests to Verified Permission out of the box
Ingress controller
  • Invokes Verified Permission in AWS for each request that needs authorization
  • (Optional) Integration of avp-local-agent to minimize number of requests to Verified Permissions
Sidecar proxy
  • Invokes Verified Permissions in AWS for each request that needs authorization
  • (Optional) Integration of avp-local-agent to minimize number of requests to Verified Permissions
Application container
  • Invokes Verified Permissions in AWS only if the business logic processing a request requires authorization
  • (Optional) Integration of avp-local-agent to minimize number of requests to Verified Permissions
Cost
API gateway
  • Consumption-based costs depending on requests received and data transferred out, and optionally cache size
  • Consumption-based costs to invoke Verified Permissions
  • Enabling a cache potentially reduces costs per requests
Ingress controller
  • Adds to infrastructure costs depending on the underlying compute resources needed to run the fleet of pods for Ingress and authorization service
  • Consumption-based costs to invoke Verified Permissions, which can be minimized by integrating avp-local-agent
Sidecar proxy
  • Adds to infrastructure costs depending on the underlying compute resources needed to run the sidecar containers for the proxy and authorization service in each pod
  • Consumption-based costs to invoke Verified Permissions, which can be minimized by integrating avp-local-agent
Application container
  • Typically minimal additional costs, since authorization code shares the application’s resources
  • Consumption-based costs to invoke Verified Permissions, which can be minimized by integrating avp-local-agent
Portability
API gateway
  • Portability is limited and depends on API Gateway with functionality for custom authorization
Ingress controller
  • Portable across Kubernetes environments with Ingress controller supporting external authorization
Sidecar proxy
  • Portable across Kubernetes environments
Application container
  • Highly portable without dependencies to underlying components
Complexity
API gateway
  • Offered as central component by platform engineering team to offload complexity of authorization from product teams
  • Changes in authorization service impact product teams
Ingress controller
  • Offered as central component by platform engineering team to offload complexity of authorization from product teams
  • Changes in authorization service impact product teams
Sidecar proxy
  • Platform engineering teams provide standardized patterns (and optionally implementation) for authorization that can be integrated and implemented by product teams
  • Increases autonomy of individual teams
Application container
  • Full responsibility for authorization lies with the product teams
  • Increases autonomy of individual teams

Not all services have the same requirements for authorization. You can also combine the patterns discussed in this post. You can, for example, put a basic authorization workflow with coarse-grained access control in front of the majority of your services. You can then rely on sidecar proxies with policy information points to inject additional, dynamic context into authorization decisions for specific services. Lastly, if certain use cases of a service demand complex authorization decisions, you can fall back to application-level authorization for specific parts of your code base.

Conclusion

In this blog post, we explored four patterns for integrating Verified Permissions into a containerized environment. We discussed the benefits and considerations of implementing Verified Permissions at different levels: from an API gateway outside of Kubernetes clusters, by means of Ingress controllers and sidecar proxies as network components inside the Kubernetes cluster, to authorization within the application itself. We saw how each pattern offers unique advantages. We also discussed considerations for finding a suitable option for your situation and when to combine patterns.

By using Verified Permissions, organizations can implement consistent, fine-grained authorization across their containerized workloads, whether they’re running on-premises, in the cloud, or in hybrid environments. This centralized approach to authorization can enhance security and simplify policy management and application development.

To learn more about implementing these patterns and best practices, visit the Amazon Verified Permissions User Guide. For hands-on experience, we recommend exploring the Verified Permissions workshop, which provides practical examples and guided exercises.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
 

Manuel Heinkel
Manuel Heinkel

Manuel is a Solutions Architect at AWS, working with software companies in Germany to build innovative and secure applications in the cloud. He supports customers in solving business challenges and achieving success with AWS. Manuel has a track record of diving deep into security and SaaS topics. Outside of work, he enjoys spending time with his family and exploring the mountains.
Markus Kokott
Markus Kokott

Markus is a Senior Solutions Architect at AWS, specializing in guiding software companies to become successful SaaS providers. With over a decade of experience in consulting as well as designing, building, and operating software products, he excels in bridging the gap between business and technology. Markus is passionate about containers, platform engineering, and DevOps in general, using his expertise to drive innovation and efficiency.

Automate the Creation & Rotation of Amazon Simple Email Service SMTP Credentials

Post Syndicated from Zip Zieper original https://aws.amazon.com/blogs/messaging-and-targeting/automate-the-creation-rotation-of-amazon-simple-email-service-smtp-credentials/

[Amazon Simple Email Service] provides a secure email solution that scales with your business needs. Unfortunately, all email systems, including Amazon SES, remain the primary target for spammers and bad actors due to email’s widespread use and accessibility.

While SES offers powerful features for application-based email sending, its SMTP credentials require careful management to prevent unauthorized access. Compromised credentials enable bad actors to send malicious emails through legitimate domains, which can bypass security filters and damage sender reputation.

To protect your SES implementation, you must encrypt SMTP credentials during storage and transmission. Additionally, implementing role-based access controls helps restrict credential access to authorized personnel only. Regular credential rotation at fixed intervals, typically every 90 days, minimizes potential security breaches. Automating this rotation process eliminates human error and ensures consistent security practices across your organization.

Problem Statement

Imagine you are the administrator for a large financial institution. You recently began using Amazon SES to send email from two dozen on-premises servers. Your email servers authenticate with SES using SMTP credentials to access the SES SMTP interface. Your organization’s security policies mandate regular credential rotation, including the ability to rotate them on-demand. How can you automate SMTP credential rotation such that you can meet your organization’s security policies?

This blog post will present two solutions that automate the secure management and automatic rotation of SMTP credentials for Amazon SES. Each will help enhance email security, comply with regulations, and minimize operational overhead.

Both solutions provide SES customers who use SMTP with additional tools to improve email security, ensure compliance, and reduce operational overhead. You can deploy the option that best suites your needs by following the guidance in this blog post.

If your environment supports automated rotation, AWS Systems Manager Documents (SSM Documents) can help by providing pre-defined or custom automation workflows for securely managing secrets rotation, deploy Option 1.

If your environment does not support automated rotation, you can still implement an auditable, managed rotation solution by storing your secrets in AWS Systems Manager Parameter Store by deploying Option 2.

As a pay-per-use platform, the underlying AWS services used in either deployment option will only charge you for the resources that you actually consume. You can leverage the AWS Pricing Calculator to estimate the run-time costs for your specific workload. Alternatively, you can work directly with your AWS account team to understand the pricing for these solutions.

Getting SES SMTP Credentials

To send emails through the Amazon SES SMTP interface, email servers must first authenticate with SES using dedicated SES SMTP credentials. Typically, a systems administrator logs into the AWS SES console, clicks the Create SMTP Credentials button, and navigates to the AWS Identity and Access Management] (IAM) console. There, the administrator creates an IAM user with permissions for SES. The administrator then uses the IAM user’s secret access key to generate the SES SMTP password, which they use to configure their email servers or SMTP-enabled applications for use with SES.

Multiple SMTP Credentials

The SES SMTP interface authenticates requests using an SMTP credential derived from an IAM user’s access key ID and secret access key. Since temporary access keys cannot be used to derive SES SMTP credentials, you must deploy and regularly rotate a long-lived key.

While the manual process of creating SES SMTP credentials works for a small number of credentials, it becomes cumbersome for customers with numerous email servers or strict password rotation policies. These customers may find the automated credential rotation mechanisms described in the following solutions better suited to their production needs.

Option 1 – Fully Automated Credential Rotation:

The fully automated version of this solution uses a custom Lambda function to create an SMTP password, which is stored in AWS Secrets Manager. AWS Secrets Manager’s built-in rotation feature then triggers the rotation of SES SMTP credentials. AWS Systems Manager Documents utilize AWS Systems Manager Agents to automatically make the changes to the authentication configuration on email servers.

The key advantages of using AWS Systems Manager to make the email server configuration changes include:

  • Ability to deploy changes to on-premises and Amazon EC2 hosts, allowing rotation of secrets across a hybrid estate.
    Customization of the document to specific email software configurations.
    Targeting the secret (SMTP credential) rotation document on all email servers based on tags.

Let’s dive deep into Option 1 – Fully Automated Credential Rotation.

Option 1 - Fully Automated Credential Rotation

How Option 1 works:

Refer to the image above for the workflow:

  1. AWS Secrets Manager initiates a rotation request, either on a schedule or via an authorized user’s request, triggering the “rotation Lambda” to rotate the SES SMTP credentials.
  2. The SES Secret Rotation Function Lambda (see figure x above):
    • a. Creates a new IAM secret access key for the designated SES IAM user, derives the new SES SMTP password, and stores it in AWS Secrets Manager.
    • b. Connects to SES to verify the new SMTP password can authenticate.
    • c. Initiates an AWS Systems Manager Run Command to update the new SMTP password on target email servers using a pre-configured Systems Manager Document.
    • d. (and e.) Monitors the status of the Systems Manager Document execution until all updates complete successfully
    • f. Deletes the old IAM access and secret access keys.

With this fully automated solution, SES SMTP credentials can be rotated on a schedule or triggered manually, with no impact to email service uptime.

Deploying the Fully Automated Solution in Your AWS Account (Option 1)

Prerequisites for the Fully Automated Solution

  1. AWS Account Access, typically with admin-level permission to allow for the deployment.
  2. Your preferred IDE with AWS CLI version 2 and named profile setup.
    • Alternatively, you can use the AWS CLI from the AWS CloudShell in your browser.
  3. Clone the Github repository (for this solution, you only need the README.md and sesautomaticrotation.yaml files found in /ses-credential-rotation/automatic-rotation).
    • git clone -b ses-credential-rotation https://github.com/aws-samples/serverless-mail.git
    • Note – We follow the principles of least privilege in this solution. The CloudFormation templates we’ve supplied require you to specify an identity, or configuration-set resource to use in the SES sending operation. You can find guidance on defining these values at Actions, resources, and condition keys for Amazon SES. Additionally, we’ve limited the IAM User to the ses:SendRawEmail action, which you can adjust as appropriate).
  4. Console access to your AWS SES account that is properly configured to send emails via at least one verified identity.
  5. Target email server(s) properly configured to send email via SES using SES SMTP authentication.
    • The AWS Systems Manager agent(s) must be correctly installed and configured on your target email server(s) as detailed in Setting up AWS Systems Manager.
    • The target email servers must be decorated with the tag (“SSMServerTag“) and value (“SSMServerTagValue“). These values allow the Systems Manager Document to identify them.
      • We use the tag “EmailServer” and the value “True” in our example, but you can use any tag and value that you wish).
  6. An email address (or list) to receive SMTP rotation notifications.
  7. Console access to your AWS Secrets Manager.
  8. Console access to your AWS Systems Manager.

Deployment Steps

  1. Clone the GitHub repository to your IDE
    • If using AWS CloudShell, ensure you are in the same region as your AWS Systems and Secrets Manager
    • run: git clone https://github.com/aws-samples/serverless-mail.git
    • Navigate to the directory ses-credential-rotation/automatic-rotation
  2. Follow the steps in README.md to
    • Create a S3 bucket to deploy the CloudFormation Template.
    • Package the Lambda functions and upload them to Amazon S3.
    • Deploy the Cloud Formation Template.
    • Update the appropriate AWS Systems Manager sample document created by the CloudFormation Template to reflect your email server environments. These can be found in the AWS Systems Manager console under Documents > Owned by me
      • The ExampleWindowsIISSMTPSESpasswordrotator sample provides an example for Microsoft Windows hosts using the runPowerShellScript action to update the server’s SMTP credentials.
      • The ExamplePostfixSESpasswordrotator sample provides an example for Linux hosts using the runShellScript action to update the server’s SMTP credentials.

Testing Option 1 – Fully Automated Credential Rotation

To test the Fully Automated Credential Rotation solution, have Secrets Manager perform an immediate rotation by following these steps:

  1. Open AWS Secrets Manager console
  2. Locate the secret SESSendSecret
  3. Select the Rotation tab
  4. Click the “Rotate Secret immediately” button.

You can track the progress of the rotation by locating the logs of the Lambda that is deployed to manage the rotation.

  1. In the AWS console, go to CloudFormationStack’s Resources tab
  2. Find the LogicalID = SESSecretRotationFunction
  3. Click the PhysicalID link to open the Lambda
  4. Under the Monitor Tab, select the “View CloudWatch logs” button in the top right
  5. The logs should show the rotation flow through 4 stages below (more details of each stage are available here):
    1. create_secret
    2. set_secret
    3. test_secret
    4. finish_secret

Option 2 – Partially Automated Credential Rotation:

The partially automated version uses a custom AWS Lambda function to create an SMTP password, which is stored in AWS Systems Manager Parameter Store. This solution simplifies credential rotation, where manual changes must be conducted by support staff. By wrapping the manual change process with AWS Step Functions, you can ensure a robust and auditable process to regularly rotate the SES SMTP credential.

How Option 2 works:

  1. The credential rotation AWS Step Function creates a new SES SMTP credential and updates it in AWS Systems Manager Parameter Store.
  2. It retrieves a list of servers from an Amazon DynamoDB table and launches a manual confirmation AWS Step Function execution for each server to initiate and track the manual step.
  3. The manual confirmation AWS Step Function emails the designated address, requesting support staff to arrange the rotation. The email includes a link specific to that server.
  4. The person completing the manual change confirms back to the AWS Step Function via the link that the rotation is complete.
  5. Once the rotation on a server is confirmed, the manual confirmation AWS Step Function for that server is marked as complete.
  6. After all server rotations are complete, the credential rotation AWS Step Function continues, disabling the old SES SMTP credential and deleting it after a few days.

AWS Step Function executions can last up to 365 days, providing sufficient time for the manual rotation and confirmation.

The screenshot below shows a graphical representation of the credential rotation AWS Step Function execution status, providing a real-time view of the rotation progress.

SMTP credential rotation AWS Step Function

You can also track the status of individual servers via the manual rotation step function execution list.

SMTP manual rotation step function execution list

The partially automated solution for rotating Amazon SES SMTP credentials is illustrated and detailed below:

Option 2 - partially automated solution

Refer to the image above for the option 2 workflow:

  1. EventBridge Scheduler Trigger: An EventBridge scheduler rule triggers a custom Starter Function Lambda (SF Lambda) on the last day of every 3rd month (this can be adjusted to suit your needs in the CloudFormation template).
  2. Credential Rotation Step Function: The Starter Function Lambda triggers the Credential Rotation AWS Step Function, providing a clearly defined name to facilitate auditing (“password-rotation-dd-mm-yy“).
  3. Credential Rotation Step Function Actions:
    1. Creates a new IAM (Identity and Access Management) secret access key for the SES IAM user.
    2. Triggers the SMTP Credential Generator Lambda to derive the SES SMTP password from the newly created IAM secret access key (using the algorithm provided in the SES documentation.
    3. Stores the new SES SMTP credential in AWS Systems Manager Parameter Store.
    4. Reads a list of servers that are utilizing this credential from a DynamoDB table.
  4. Manual Confirmation Step Function:
    1. For each server, a manual confirmation AWS Step Function is triggered, sending a message on the Amazon Simple Notification Service (SNS) topic.
    2. The SNS notification prompts the server administrator via email to manually rotate the SMTP credentials on the on-premises email server.
    3. The server administrator uses a link in the email to confirm the credential has been rotated and tested on the server.
    4. The link triggers the Confirmation Lambda exposed via API Gateway, which marks the ManualConfirmation step function as complete.
  5. Credential Rotation Completion: The CredentialRotation step function waits until all manual confirmation step functions have completed before proceeding.
  6. Old IAM Access Key Deletion: Once confirmation has been received for all servers, the step function deletes the old IAM access key.

Deployment

To deploy the partially automated solution in your AWS account, you will need the following prerequisites:

Prerequisites for the Partially Automated Solution

  1. AWS Account Access, typically with admin-level permission to allow for the deployment.
  2. Your preferred IDE with AWS CLI version 2 and named profile setup. Alternatively, you can use the AWS CLI from the AWS CloudShell in your browser.
  3. SES enabled, configured, and properly sending emails.
  4. External email server(s) currently configured to use SES with SMTP.
  5. Administrator email address to receive notifications.
  6. AWS Secrets Manager and AWS Systems Manager set up.
  7. AWS Systems Manager agent(s) correctly installed and configured on your target email servers as detailed in Setting up AWS Systems Manager.
  8. Amazon EC2 instance with Postfix configured to send emails through SES
  9. Target email servers must be decorated with a tag (“SSMServerTag“) and value (“SSMServerTagValue“) that will be used to identify them by the Systems Manager Document (we used “server” and “email”)
  10. AWS Parameter Store and AWS Step Functions.

Once you have the prerequisites in place, follow the instructions in the GitHub project.

Conclusion

Implementing an automated credential rotation process for Amazon SES SMTP enhances security and compliance, streamlines operations, and reduces the risk of downtime and human error. By leveraging AWS Secrets Manager and AWS Systems Manager (option 1) or AWS Systems Manager Parameter Store and Step Functions (option 2), organizations can centralize SES SMTP credential management, maintain an audit trail, and quickly update email application servers with new SMTP credentials.

Need additional guidance?

Best practices for rapidly deploying Landing Zone Accelerator on AWS

Post Syndicated from Lei Shi original https://aws.amazon.com/blogs/devops/best-practices-for-rapidly-deploying-landing-zone-accelerator-on-aws/

Landing Zone Accelerator on AWS (LZA) enables customers to deploy a flexible, configuration-driven solution to establish a landing zone while also leveraging AWS Control Tower. At AWS Professional Services, we’ve helped customers deploy and configure LZA hundreds of times. A common request we encounter is integrating LZA configuration into customers’ existing GitOps workflows. GitOps has emerged as a leading model for Infrastructure as Code (IaC), helping organizations automate and manage their cloud infrastructure. The model uses Git repositories as the single source of truth for infrastructure configuration, enabling teams to maintain consistent, version-controlled environments.

In this blog, we will focus on common LZA implementation steps based on our experience, helping customers jump-start their LZA environment and implement GitOps for their AWS infrastructure management. First, we will demonstrate how to leverage LZA while complying with your organization’s policies such as private package repositories. Next, we will guide you through a new installation of LZA that takes advantage of an auto-generated starter set of configuration files. Finally, we will direct you to another blog post that will enable you to leverage GitOps for ongoing management of your LZA configuration.

Architecture overview

The LZA solution leverages two distinct repositories; one for the LZA source code, and another for your organization’s specific configuration files. LZA creates two separate AWS CodePipelines , which are used to install the LZA solution and apply your organization’s specific configuration. Figure 1 illustrates the association between repositories and pipelines. By default, when installing LZA, the solution uses GitHub as the source and pulls the installation files published by AWS from the official LZA GitHub repository.

a diagram with icons illustrating LZA solution components

Figure 1. Landing Zone Accelerator solution components

Deploy LZA as a new install

Step 1: Preparing your enterprise private GitHub to host LZA source code.
Customers may choose to deploy LZA from the official AWS GitHub repository for LZA, but we often we find customers have policies in place that require these types of packages to be deployed from a private repository managed by the organization. For customers using GitHub privately in their enterprise, this can be as easy as cloning the LZA source code repository into your own private GitHub repository, enabling you to take advantage of policies and controls within your organization. Before moving to the next step, take a moment and clone the repository into your own private repository. A GitHub personal access token stored in AWS Secrets Manager is required to enable the stack to access your private repository. Before deploying LZA, follow these instructions to enable stack access to your repository.

Step 2: In the organization management account, install LZA as a CloudFormation Stack.

To get started, we will be going through a new installation of the LZA solution. The following steps provide specific parameter options to the CloudFormation template to support a new installation of LZA.

Specify the following parameters for Source Code Repository Configuration, see Figure 2.

  1. For Stack name, specify a name you like.
  2. For Source Location, choose github.
  3. For Repository Owner, specify your GitHub account owner ID.
  4. For Repository Name, specify your cloned LZA source code repository
  5. For Branch Name, specify the branch name of your LZA source code repository.

a screenshot of a set of parameters setting of LZA source code repo in a cloudformation stack

Figure 2. LZA installer stack parameters – source code repository

Specify the following parameters for Configuration Repository Configuration, see Figure 3.

  1. For Configuration Repository Location, choose s3.
  2. For Use Existing Config Repository, choose No.
  3. For Existing Config Repository Name, Existing Config Repository Branch Name, Existing Config Repository Owner, and Existing Config Repository CodeConnection ARN, leave blank.

We intentionally want to use S3 for the configuration repository because as the LZA solution is installed, it will auto-generate a set of starter configuration YAML files and deploy them for us in S3. This makes it very easy to get started with an initial set of customized YAML files for your environment. We choose “No” in the Use Existing Config Repository field, to have LZA to perform a new LZA installation.

a screenshot of a set of parameters setting of LZA configuration repo in a cloudformation stack

Figure 3. LZA installer stack parameters – configuration repository

  1. Choose Next, and complete the remainder of the stack settings.
  2. Finally, choose Create stack to launch the CloudFormation stack.

The installer stack typically takes minutes to complete (See Figure 4).

a screenshot showing LZA installation cloudformation stack completed successfully

Figure 4. LZA installer stack completion

Step 3: Validate two LZA pipelines are created and successfully completed in AWS CodePipeline console.

After the CloudFormation stack completes, open the AWS CodePipeline console. You’ll see a new pipeline named “AWSAccelerator-Installer” running (See Figure 5). This is the LZA Installer pipeline, and it’s connected to the GitHub source repository you specified in Step 2 above with parameters from 2 to 5. This Installer pipeline automatically generates a set of LZA configuration files stored as a compressed ZIP archive in Amazon S3. It will be designated as configuration repository of the LZA solution.

a screenshot showing LZA installer pipeline created in AWS CodePipeline successfully

Figure 5. AWSAccelerator-Installer pipeline creation

When the AWSAccelerator-Installer pipeline completes, the solution automatically creates and runs a second pipeline named “AWSAccelerator-Pipeline” as shown in Figure 6. This pipeline connects to both the GitHub source repository, and the newly created configuration repository in Amazon S3. The AWSAccelerator-Pipeline is the pipeline that manages your landing zone deployment and customization.

a screenshot showing LZA core pipeline created in AWS CodePipeline successfully

Figure 6. AWSAccelerator-Pipeline created from the AWSAccelerator-Installer pipeline

After the AWSAccelerator-Pipeline completes, your LZA solution is ready for customization.

Step 4: Migrate the LZA configuration repository from S3 to GitHub

With the AWSAccelerator-Pipeline completed, your initial landing zone is now deployed, leveraging the configuration stored in your S3 bucket. For some customers, they may need to ensure that changes to the landing zone configuration are controlled through their existing GitOps processes and tooling. See Figure 7 as an example where the S3 configuration files have been copied to a customer owned GitHub repository. This transition step can be performed in future LZA upgrade window when there is a new release of LZA source code, or right after the initial LZA installation completes in Step 3. For more information on migrating from S3 to GitHub, follow this guide to configure your AWSAccelerator-Pipelines with AWS CodeConnection.

a diagram with icons illustrating LZA solution new components with LZA configuration repo migrated to GitHub

Figure 7. CodeConnection based LZA Configuration Repository

Conclusion

In this post, we explored key steps to streamline your LZA implementation journey. By demonstrating how to work with your private package repositories, providing guidance on leveraging auto-generated configuration files, and introducing GitOps-based management, we’ve outlined a practical path to establish and maintain a robust AWS infrastructure foundation. These approaches can significantly reduce the time and complexity typically associated with LZA deployments while ensuring compliance with organizational policies. We encourage you to try these implementation steps and explore the referenced resources to enhance your AWS cloud operations. For more information about Landing Zone Accelerator, visit the AWS Landing Zone Accelerator on GitHub.

About the authors

author photo of Lei Shi

Lei Shi

Lei Shi is a Delivery Consultant at AWS Professional Services, where he transforms complex cloud challenges into elegant solutions. He focuses on enabling organizations to build secure and scalable cloud environments throughout their AWS journey.

author photo of Adam Spicer

Adam Spicer

Adam Spicer is a Principal Cloud Architect for AWS Professional Services. He works with enterprise customers to design and build their cloud infrastructure and automation to accelerate their migration to AWS. He is an avid FSU Seminole fan who loves to be on outdoor adventures with his family.

Design patterns for implementing Hive Metastore for Amazon EMR on EKS

Post Syndicated from Avinash Desireddy original https://aws.amazon.com/blogs/big-data/design-patterns-for-implementing-hive-metastore-for-amazon-emr-on-eks/

In modern data architectures, the need to manage and query vast datasets efficiently, consistently, and accurately is paramount. For organizations that deal with big data processing, managing metadata becomes a critical concern. This is where Hive Metastore (HMS) can serve as a central metadata store, playing a crucial role in these modern data architectures.

HMS is a central repository of metadata for Apache Hive tables and other data lake table formats (for example, Apache Iceberg), providing clients (such as Apache Hive, Apache Spark, and Trino) access to this information using the Metastore Service API. Over time, HMS has become a foundational component for data lakes, integrating with a diverse ecosystem of open source and proprietary tools.

In non-containerized environments, there was typically only one approach to implementing HMS—running it as a service in an Apache Hadoop cluster. With the advent of containerization in data lakes through technologies such as Docker and Kubernetes, multiple options for implementing HMS have emerged. These options offer greater flexibility, allowing organizations to tailor HMS deployment to their specific needs and infrastructure.

In this post, we will explore the architecture patterns and demonstrate their implementation using Amazon EMR on EKS with Spark Operator job submission type, guiding you through the complexities to help you choose the best approach for your use case.

Solution overview

Prior to Hive 3.0, HMS was tightly integrated with Hive and other Hadoop ecosystem components. Hive 3.0 introduced a Standalone Hive Metastore. This new version of HMS functions as an independent service, decoupled from other Hive and Hadoop components such as HiveServer2. This separation enables various applications, such as Apache Spark, to interact directly with HMS without requiring a full Hive and Hadoop environment installation. You can learn more about other components of Apache Hive on the Design page.

In this post, we will use a Standalone Hive Metastore to illustrate the architecture and implementation details of various design patterns. Any reference to HMS refers to a Standalone Hive Metastore.

The HMS broadly consists of two main components:

  • Backend database: The database is a persistent data store that holds all the metadata, such as table schemas, partitions, and data locations.
  • Metastore service API: The Metastore service API is a stateless service that manages the core functionality of the HMS. It handles read and write operations to the backend database.

Containerization and Kubernetes offers various architecture and implementation options for HMS, including, running:

In this post, we’ll use Apache Spark as the data processing framework to demonstrate these three architectural patterns. However, these patterns aren’t limited to Spark and can be applied to any data processing framework, such as Hive or Trino, that relies on HMS for managing metadata and accessing catalog information.

Note that in a Spark application, the driver is responsible for querying the metastore to fetch table schemas and locations, then distributes this information to the executors. Executors process the data using the locations provided by the driver, never needing to query the metastore directly. Hence, in the three patterns described in the following sections, only the driver communicates with the HMS, not the executors.

HMS as sidecar container

In this pattern, HMS runs as a sidecar container within the same pod as the data processing framework, such as Apache Spark. This approach uses Kubernetes multi-container pod functionality, allowing both HMS and the data processing framework to operate together in the same pod. The following figure illustrates this architecture, where the HMS container is part of Spark driver pod.

HMS as sidecar container

This pattern is suited for small-scale deployments where simplicity is the priority. Because HMS is co-located with the Spark driver, it reduces network overhead and provides a straightforward setup. However, it’s important to note that in this approach HMS operates exclusively within the scope of the parent application and isn’t accessible by other applications. Additionally, row conflicts might arise when multiple jobs attempt to insert data into the same table simultaneously. To address this, you should make sure that no two jobs are writing to the same table simultaneously.

Consider this approach if you prefer a basic architecture. It’s ideal for organizations where a single team manages both the data processing framework (for example, Apache Spark) and HMS, and there’s no need for other applications to use HMS.

Cluster dedicated HMS

In this pattern, HMS runs in multiple pods managed through a Kubernetes deployment, typically within a dedicated namespace in the same data processing EKS cluster. The following figure illustrates this setup, with HMS decoupled from Spark driver pods and other workloads.

Cluster dedicated HMS

This pattern works well for medium-scale deployments where moderate isolation is enough, and compute and data needs can be handled within a few clusters. It provides a balance between resource efficiency and isolation, making it ideal for use cases where scaling metadata services independently is important, but complete decoupling isn’t necessary. Additionally, this pattern works well when a single team manages both the data processing frameworks and HMS, ensuring streamlined operations and alignment with organizational responsibilities.

By decoupling HMS from Spark driver pods, it can serve multiple clients, such as Apache Spark and Trino, while sharing cluster resources. However, this approach might lead to resource contention during periods of high demand, which can be mitigated by enforcing tenant isolation on HMS pods.

External HMS

In this architecture pattern, HMS is deployed in its own EKS cluster deployed using Kubernetes deployment and exposed as a Kubernetes Service using AWS Load Balancer Controller, separate from the data processing clusters. The following figure illustrates this setup, where HMS is configured as an external service, separate from the data processing clusters.

External HMS

This pattern suits scenarios where you want a centralized metastore service shared across multiple data processing clusters. HMS allows different data teams to manage their own data processing clusters while relying on the shared metastore for metadata management. By deploying HMS in a dedicated EKS cluster, this pattern provides maximum isolation, independent scaling, and the flexibility to operate and managed as its own independent service.

While this approach offers clear separation of concerns and the ability to scale independently, it also introduces higher operational complexity and potentially increased costs because of the need to manage an additional cluster. Consider this pattern if you have strict compliance requirements, need to ensure complete isolation for metadata services, or want to provide a unified metadata catalog service for multiple data teams. It works well in organizations where different teams manage their own data processing frameworks and rely on a shared metadata store for data processing needs. Additionally, the separation enables specialized teams to focus on their respective areas.

Deploy the solution

In the remainder of this post, you will explore the implementation details for each of the three architecture patterns, using EMR on EKS with Spark Operator job submission type as an example to demonstrate their implementation. Note that this implementation hasn’t been tested with other EMR on EKS Spark job submission types. You will begin by deploying the common components that serve as the foundation for all the architecture patterns. Next, you’ll deploy the components specific to each pattern. Finally, you’ll execute Spark jobs to connect to the HMS implementation unique to each pattern and verify the successful execution and retrieval of data and metadata.

To streamline the setup process, we’ve automated the deployment of common infrastructure components so you can focus on the essential aspects of each HMS architecture. We’ll provide detailed information to help you understand each step, simplifying the setup while preserving the learning experience.

Scenario

To showcase the patterns, you will create three clusters:

  • Two EMR on EKS clusters: analytics-cluster and datascience-cluster
  • An EKS cluster: hivemetastore-cluster

Both analytics-cluster and datascience-cluster serve as data processing clusters that run Spark workloads, while the hivemetastore-cluster hosts the HMS.

You will use analytics-cluster to illustrate the HMS as sidecar and cluster dedicated pattern. You will use all three clusters to demonstrate the external HMS pattern.

Source code

You can find the codebase in the AWS Samples GitHub repository.

Prerequisites

Before you deploy this solution, make sure that the following prerequisites are in place:

Set up common infrastructure

Begin by setting up the infrastructure components that are common to all three architectures.

  1. Clone the repository to your local machine and set the two environment variables. Replace <AWS_REGION> with the AWS Region where you want to deploy these resources.
git clone https://github.com/aws-samples/sample-emr-eks-hive-metastore-patterns.git
cd sample-emr-eks-hive-metastore-patterns
export REPO_DIR=$(pwd)
export AWS_REGION=<AWS_REGION>
  1. Execute the following script to create the shared infrastructure.
cd ${REPO_DIR}/setup
./setup.sh
  1. To verify successful infrastructure deployment, navigate to the AWS Management Console for AWS CloudFormation, select your stack, and check the Events, Resources, and Outputs tabs for completion status, details, and list of resources created.

You have completed the setup of the common components that serve as the foundation for all architectures. You will now deploy the components specific to each architecture and execute Apache Spark jobs to validate the successful implementation.

HMS in a sidecar container

To implement HMS using the sidecar container pattern, the Spark application requires setting both sidecar and catalog properties in the job configuration file.

  1. Execute the following script to configure the analytics-cluster for sidecar pattern. For this post, we stored the HMS database credentials into a Kubernetes Secret object. We recommend using Kubernetes External Secrets Operator to fetch HMS database credentials from AWS Secrets Manager.
cd ${REPO_DIR}/hms-sidecar
./configure-hms-sidecar.sh analytics-cluster
  1. Review the Spark job manifest file spark-hms-sidecar-job.yaml. This file was created by substituting variables in the spark-hms-sidecar-job.tpl template in the previous step. The following samples highlight key sections of the manifest file.
spec:
  driver:
  ...
    sidecars:
      # Hive Metastore Sidecar container
      - name: hive-metastore
        image: ${AWS_ACCOUNT_ID}.dkr.ecr.${AWS_REGION}.amazonaws.com/hive-metastore:latest
        env:
          # These settings configure metastore to use Amazon Postgres RDS as backend database, connecting to it via jdbc URL.
          - name: HIVE_METASTORE_DB_TYPE
            value: postgres
          - name: HIVE_METASTORE_DB_DRIVER
            value: org.postgresql.Driver
          - name: HIVE_METASTORE_DB_URL
            value: jdbc:postgresql://${HMS_RDS_PROXY_ENDPOINT}:5432/hivemetastore
          # The warehouse location is specified as an S3 bucket
          - name: HIVE_METASTORE_WAREHOUSE_LOC
            value: s3a://${S3_BUCKET_NAME}/warehouse
          - name: AWS_REGION
            value: ${AWS_REGION}
          # The database username and password are passed via environment variables. The password is retrieved from a Kubernetes secret
          - name: HIVE_METASTORE_DB_USER
            value: hive_metastore_user
          - name: HIVE_METASTORE_DB_PASSWORD
            valueFrom:
              secretKeyRef:
                name: hms-rds-password
                key: HIVE_METASTORE_DB_PASSWORD

Spark job configuration

spec:  
  sparkConf:
    # Hive Catalog properties
    # Sets spark to use Hive as the catalog for SQL operations
    spark.sql.catalogImplementation: "hive"
    # HMS is exposed on localhost:8080 since the sidecar runs in the same pod. Spark connects to the sidecar via this URI
    spark.hadoop.hive.metastore.uris: "thrift://localhost:9083"
    # The data location is set to S3 bucket
    spark.sql.warehouse.dir: "s3a://${S3_BUCKET_NAME}/warehouse"
    # Retrieve temporary AWS credentials by assuming a role using a web identity token
    spark.hadoop.fs.s3a.aws.credentials.provider: "com.amazonaws.auth.WebIdentityTokenCredentialsProvider"
    # Configure Spark to use S3A filesystem
    spark.hadoop.fs.s3a.impl: "org.apache.hadoop.fs.s3a.S3AFileSystem"

Submit the Spark job and verify the HMS as sidecar container setup

In this pattern, you will submit Spark jobs in analytics-cluster. The Spark jobs will connect to the HMS service running as a sidecar container in the driver pod.

  1. Run the Spark job to verify that the setup was successful.
kubectl apply -f spark-hms-sidecar-job.yaml
  1. Describe the sparkapplication object.
kubectl get sparkapplication -n emr
kubectl describe sparkapplication spark-hms-sidecar-job --namespace emr
  1. List the pods and observe the number of containers attached to the driver pod. Wait until the Status changes from ContainerCreating to Running (should take just a few seconds).
kubectl get pods -n emr
  1. View the driver logs to validate the output.
kubectl logs spark-hms-sidecar-job-driver --namespace emr
  1. If you encounter the following error, wait for a few minutes and rerun the previous command.
Error from server (BadRequest): container "spark-kubernetes-driver" in pod "spark-hms-sidecar-driver" is waiting to start: ContainerCreating
  1. After successful completion of the job, you see the following message in the logs. The tabular output successfully validates the setup of HMS as a sidecar container.
...
24/09/17 21:44:00 INFO metastore: Trying to connect to metastore with URI thrift://localhost:9083
24/09/17 21:44:00 INFO metastore: Opened a connection to metastore, current connections: 1
24/09/17 21:44:00 INFO metastore: Connected to metastore.
...
...
+-------+---+-------+---+
|pattern|id |name   |age|
+-------+---+-------+---+
|Sidecar|1 |Alice   |30 |
|Sidecar|2 |Bob     |25 |
|Sidecar|3 |Charlie |35 |
+-------+---+-------+---+

Cluster dedicated HMS

To implement HMS using a cluster dedicated HMS pattern, the Spark application requires setting up HMS URI and catalog properties in the job configuration file.

  1. Execute the following script to configure the analytics-cluster for cluster dedicated pattern.
cd ${REPO_DIR}/hms-cluster-dedicated
./configure-hms-cluster-dedicated.sh analytics-cluster
  1. Verify the HMS deployment by listing the pods and viewing the logs. No Java exceptions in the logs confirms that the Hive Metastore service is running successfully.
kubectl get pods --namespace hive-metastore
kubectl logs <HMS-PODNAME> --namespace hive-metastore
  1. Review the Spark job manifest file, spark-hms-cluster-dedicated-job.yaml. This file is created by substituting variables in the spark-hms-cluster-dedicated-job.tpl template in the previous step. The following sample highlights key sections of the manifest file.
spec: 
  sparkConf:
    # Hive Catalog properties
    # Sets spark to use Hive as the catalog for SQL operations
    spark.sql.catalogImplementation: "hive"
    # HMS is running in a pod and we can connect to it in the same EKS cluster via this URI
    spark.hadoop.hive.metastore.uris: "thrift://hive-metastore-svc.hive-metastore.svc.cluster.local:9083"
    # The data location is set to S3 bucket
    spark.sql.warehouse.dir: "s3a://${S3_BUCKET_NAME}/warehouse"
    # Retrieve temporary AWS credentials by assuming a role using a web identity token
    spark.hadoop.fs.s3a.aws.credentials.provider: "com.amazonaws.auth.WebIdentityTokenCredentialsProvider"
    # Configure Spark to use S3A filesystem
    spark.hadoop.fs.s3a.impl: "org.apache.hadoop.fs.s3a.S3AFileSystem"

Submit the Spark job and verify the cluster dedicated HMS setup

In this pattern, you will submit Spark jobs in analytics-cluster. The Spark jobs will connect to the HMS service in the same data processing EKS cluster.

  1. Submit the job.
kubectl apply -f spark-hms-cluster-dedicated-job.yaml -n emr
  1. Verify the status.
kubectl get sparkapplication -n emr
kubectl describe sparkapplication spark-hms-cluster-dedicated-job --namespace emr
  1. Describe driver pod and observe the number of containers attached to the driver pod. Wait until the status changes from ContainerCreating to Running (should take just a few seconds).
kubectl get pods -n emr
  1. View the driver logs to validate the output.
kubectl logs spark-hms-cluster-dedicated-job-driver --namespace emr
  1. After successful completion of the job, you should see the following message in the logs. The tabular output successfully validates the setup of cluster dedicated HMS.
...
24/09/17 21:44:00 INFO metastore: Trying to connect to metastore with URI thrift://hive-metastore-svc.hive-metastore.svc.cluster.local:9083
24/09/17 21:44:00 INFO metastore: Opened a connection to metastore, current connections: 1
24/09/17 21:44:00 INFO metastore: Connected to metastore.
...
...
+-----------------+---+-------+---+
|pattern          |id |name   |age|
+-----------------+---+-------+---+
|Cluster Dedicated|1  |Alice  |30 |
|Cluster Dedicated|2  |Bob    |25 |
|Cluster Dedicated|3  |Charlie|35 |
+-----------------+---+-------+---+

External HMS

To implement an external HMS pattern, the Spark application requires setting up an HMS URI for the service endpoint exposed by hivemetastore-cluster.

  1. Execute the following script to configure hivemetastore-cluster for External HMS pattern.
cd ${REPO_DIR}/hms-external
./configure-hms-external.sh
  1. Review the Spark job manifest file spark-hms-external-job.yaml. This file is created by substituting variables in the spark-hms-external-job.tpl template during the setup process. The following sample highlights key sections of the manifest file.
spec:
  sparkConf:
    # Hive Catalog properties
    # Sets spark to use Hive as the catalog for SQL operations
    spark.sql.catalogImplementation: "hive"
    # HMS is running in a cluster and we can connect to it in the EKS cluster via this URI
    spark.hadoop.hive.metastore.uris: "thrift://${HMS_URI_ENDPOINT}:9083"
    # The data location is set to S3 bucket
    spark.sql.warehouse.dir: "s3a://${S3_BUCKET_NAME}/warehouse"
    # Retrieve temporary AWS credentials by assuming a role using a web identity token
    spark.hadoop.fs.s3a.aws.credentials.provider: "com.amazonaws.auth.WebIdentityTokenCredentialsProvider"
    # Configure Spark to use S3A filesystem
    spark.hadoop.fs.s3a.impl: "org.apache.hadoop.fs.s3a.S3AFileSystem"

Submit the Spark job and verify the HMS in a separate EKS cluster setup

To verify the setup, submit Spark jobs in analytics-cluster and datascience-cluster. The Spark jobs will connect to the HMS service in the hivemetastore-cluster.

Use the following steps for analytics-cluster and then for datascience-cluster to verify that both clusters can connect to the HMS on hivemetastore-cluster.

  1. Run the spark job to test the successful setup. Replace <CONTEXT_NAME> with Kubernetes context for analytics-cluster and then for datascience-cluster.
kubectl config use-context <CONTEXT_NAME>
kubectl apply -f spark-hms-external-job.yaml -n emr
  1. Describe the sparkapplication object.
kubectl get sparkapplication spark-hms-external-job -n emr
kubectl describe sparkapplication spark-hms-external-job --namespace emr
  1. List the pods and observe the number of containers attached to the driver pod. Wait until the status changes from ContainerCreating to Running (should take just a few seconds).
kubectl get pods -n emr
  1. View the driver logs to validate the output on the data processing cluster.
kubectl logs spark-hms-external-job-driver --namespace emr
  1. The output should look like the following. The tabular output successfully validates the setup of HMS in a separate EKS cluster.
After successful completion of the job, you should be able to see the below message in the logs.
...
24/09/17 21:44:00 INFO metastore: Trying to connect to metastore with URI  thrift://k8s-hivemeta-hmsexter-xxxxxx.elb.us-east-1.amazonaws.com:9083
24/09/17 21:44:00 INFO metastore: Opened a connection to metastore, current connections: 1
24/09/17 21:44:00 INFO metastore: Connected to metastore.
...
...
+--------+---+-------+---+
|pattern |id |name   |age|
+--------+---+-------+---+
|External|1  |Alice  |30 |
|External|2  |Bob    |25 |
|External|3  |Charlie|35 |
+--------+---+-------+---+

Clean up

To avoid incurring future charges from the resources created in this tutorial, clean up your environment after you’ve completed the steps. You can do this by running the cleanup.sh script, which will safely remove all the resources provisioned during the setup.

cd ${REPO_DIR}/setup
./cleanup.sh

Conclusion

In this post, we’ve explored the design patterns for implementing the Hive Metastore (HMS) with EMR on EKS with Spark Operator, each offering distinct advantages depending on your requirements. Whether you choose to deploy HMS as a sidecar container within the Apache Spark Driver pod, or as a Kubernetes deployment in the data processing EKS cluster, or as an external HMS service in a separate EKS cluster, the key considerations revolve around communication efficiency, scalability, resource isolation, high availability, and security.

We encourage you to experiment with these patterns in your own setups, adapting them to fit your unique workloads and operational needs. By understanding and applying these design patterns, you can optimize your Hive Metastore deployments for performance, scalability, and security in your EMR on EKS environments. Explore further by deploying the solution in your AWS account and share your experiences and insights with the community.


About the Authors

Avinash Desireddy is a Cloud Infrastructure Architect at AWS, passionate about building secure applications and data platforms. He has extensive experience in Kubernetes, DevOps, and enterprise architecture, helping customers containerize applications, streamline deployments, and optimize cloud-native environments.

Suvojit Dasgupta is a Principal Data Architect at AWS. He leads a team of skilled engineers in designing and building scalable data solutions for AWS customers. He specializes in developing and implementing innovative data architectures to address complex business challenges.

Governing streaming data in Amazon DataZone with the Data Solutions Framework on AWS

Post Syndicated from Vincent Gromakowski original https://aws.amazon.com/blogs/big-data/governing-streaming-data-in-amazon-datazone-with-the-data-solutions-framework-on-aws/

Effective data governance has long been a critical priority for organizations seeking to maximize the value of their data assets. It encompasses the processes, policies, and practices an organization uses to manage its data resources. The key goals of data governance are to make data discoverable and usable by those who need it, accurate and consistent, secure and protected from unauthorized access or misuse, and compliant with relevant regulations and standards. Data governance involves establishing clear ownership and accountability for data, including defining roles, responsibilities, and decision-making authority related to data management.

Traditionally, data governance frameworks have been designed to manage data at rest—the structured and unstructured information stored in databases, data warehouses, and data lakes. Amazon DataZone is a data governance and catalog service from Amazon Web Services (AWS) that allows organizations to centrally discover, control, and evolve schemas for data at rest including AWS Glue tables on Amazon Simple Storage Service (Amazon S3), Amazon Redshift tables, and Amazon SageMaker models.

However, the rise of real-time data streams and streaming data applications impacts data governance, necessitating changes to existing frameworks and practices to effectively manage the new data dynamics. Governing these rapid, decentralized data streams presents a new set of challenges that extend beyond the capabilities of many conventional data governance approaches. Factors such as the ephemeral nature of streaming data, the need for real-time responsiveness, and the technical complexity of distributed data sources require a reimagining of how we think about data oversight and control.

In this post, we explore how AWS customers can extend Amazon DataZone to support streaming data such as Amazon Managed Streaming for Apache Kafka (Amazon MSK) topics. Developers and DevOps managers can use Amazon MSK, a popular streaming data service, to run Kafka applications and Kafka Connect connectors on AWS without becoming experts in operating it. We explain how they can use Amazon DataZone custom asset types and custom authorizers to: 1) catalog Amazon MSK topics, 2) provide useful metadata such as schema and lineage, and 3) securely share Amazon MSK topics across the organization. To accelerate the implementation of Amazon MSK governance in Amazon DataZone, we use the Data Solutions Framework on AWS (DSF), an opinionated open source framework that we announced earlier this year. DSF relies on AWS Cloud Development Kit (AWS CDK) and provides several AWS CDK L3 constructs that accelerate building data solutions on AWS, including streaming governance.

High-level approach for governing streaming data in Amazon DataZone

To anchor the discussion on supporting streaming data in Amazon DataZone, we use Amazon MSK as an integration example, but the approach and the architectural patterns remain the same for other streaming services (such as Amazon Kinesis Data Streams). At a high level, to integrate streaming data, you need the following capabilities:

  • A mechanism for the Kafka topic to be represented in the Amazon DataZone catalog for discoverability (including the schema of the data flowing inside the topic), tracking of lineage and other metadata, and for consumers to request access against.
  • A mechanism to handle the custom authorization flow when a consumer triggers the subscription grant to an environment. This flow consists of the following high-level steps:
    • Collect metadata of target Amazon MSK cluster or topic that’s being subscribed to by the consumer
    • Update the producer Amazon MSK cluster’s resource policy to allow access from the consumer role
    • Provide Kafka topic level AWS Identity and Access Management (IAM) permission to the consumer roles (more on this later) so that it has access to the target Amazon MSK cluster
    • Finally, update the internal metadata of Amazon DataZone so that it’s aware of the existing subscription between producer and consumer

Amazon DataZone catalog

Before you can represent the Kafka topic as an entry in the Amazon DataZone catalog, you need to define:

  1. A custom asset type that describes the metadata that’s needed to describe a Kafka topic. To describe the schema as part of the metadata, use the built-in form type amazon.datazone.RelationalTableFormType and create two more custom form types:
    1. MskSourceReferenceFormType that contains the cluster_ARN and the cluster_type. The type is used to determine whether the Amazon MSK cluster is provisioned or serverless, given that there’s a different process to grant consume permissions.
    1. KafkaSchemaFormType, which contains various metadata on the schema, including the kafka_topic, the schema_version, schema_arn, registry_arn, compatibility_mode (for example, backward-compatible or forward-compatible) and data_format (for example, Avro or JSON), which is helpful if you plan to integrate with the AWS Glue Schema registry.
  1. After the custom asset type has been defined, you can now create an asset based on the custom asset type. The asset describes the schema, the Amazon MSK cluster, and the topic that you want to be made discoverable and accessible to consumers.

Data source for Amazon MSK clusters with AWS Glue Schema registry

In Amazon DataZone, you can create data sources for AWS Glue Data Catalog to import technical metadata of database tables from AWS Glue and have the assets registered in the Amazon DataZone project. For importing metadata related to Amazon MSK, you need to use a custom data source, which can be an AWS Lambda function, using the Amazon DataZone APIs.

We provide as part of the solution a custom Amazon MSK data source with the AWS Glue Schema registry, for automating the creation, update, and deletion of custom Amazon MSK assets. It uses AWS Lambda to extract schema definitions from a Schema registry and metadata from the Amazon MSK clusters and then creates or updates the corresponding assets in Amazon DataZone.

Before explaining how the data source works, you need to know that every custom asset in Amazon DataZone has a unique identifier. When the data source creates an asset, it stores the asset’s unique identifier in Parameter Store, a capability of AWS Systems Manager.

The steps for how the data source works are as follows:

  1. The Amazon MSK AWS Glue Schema registry data source can be scheduled to be triggered on a given interval or by listening to AWS Glue Schema events such as Create, Update or Delete Schema. It can also be invoked manually through the AWS Lambda console.
  2. When triggered, it retrieves all the existing unique identifiers from Parameter Store. These parameters serve as reference to identify if an Amazon MSK asset already exists in Amazon DataZone.
  3. The function lists the Amazon MSK clusters and retrieves the Amazon Resource Name (ARN) for the given Amazon MSK name and additional metadata related to the Amazon MSK cluster type (serverless or provisioned). This metadata will be used later by the custom authorization flow.
  4. Then the function lists all the schemas in the Schema registry for a given registry name. For each schema, it retrieves the latest version and schema definition. The schema definition is what will allow you to add schema information when creating the asset in Amazon DataZone.
  5. For each schema retrieved in the Schema registry, the Lambda function checks if the assets already exist by looking into the Systems Manager parameters retrieved in the second step.
    1. If the asset exists, the Lambda function updates the asset in Amazon DataZone, creating a new revision with the updated schema or forms.
    2. If the asset doesn’t exist, the Lambda function creates the asset in Amazon DataZone and stores its unique identifier in Systems Manager for future reference.
  6. If there are schemas registered in Parameter Store that are no longer in the Schema registry, the data source deletes the corresponding Amazon DataZone assets and removes the associated parameters from Systems Manager.

The Amazon MSK AWS Glue Schema registry data source for Amazon DataZone enables seamless registration of Kafka topics as custom assets in Amazon DataZone. It does require that the topics in the Amazon MSK cluster are using the Schema registry for schema management.

Custom authorization flow

For managed assets such as AWS Glue Data Catalog and Amazon Redshift assets, the process to grant access to the consumer is managed by Amazon DataZone. Custom asset types are considered unmanaged assets, and the process to grant access needs to be implemented outside of Amazon DataZone.

The high-level steps for the end-to-end flow are as follows:

  1. (Conditional) If the consumer environment doesn’t have a subscription target, create it through the CreateSubscriptionTarget API call. The subscription target tells Amazon DataZone which environments are compatible with an asset type.
  2. The consumer triggers a subscription request by subscribing to the relevant streaming data asset through the Amazon DataZone portal.
  3. The producer receives the subscription request and approves (or denies) the request.
  4. After the subscription request has been approved by the producer, the consumer can observe the streaming data asset in their project under the Subscribed data section.
  5. The consumer can opt to trigger a subscription grant to a target environment directly from the Amazon DataZone portal, and this action triggers the custom authorization flow.

For steps 2–4, you rely on the default behavior of Amazon DataZone and no change is required. The focus of this section is then step 1 (subscription target) and step 5 (subscription grant process).

Subscription target

Amazon DataZone has a concept called environments within a project, which indicates where the resources are located and the related access configuration (for example, the IAM role) that is used to access those resources. To allow an environment to have access to the custom asset type, consumers have to use the Amazon DataZone CreateSubscriptionTarget API prior to the subscription grants. The creation of the subscription target is a one-time operation per custom asset type per environment. In addition, the authorizedPrincipals parameter inside the CreateSubscriptionTarget API lists the various IAM principals given access to the Amazon MSK topic as part of the grant authorization flow. Lastly, when calling CreateSubscriptionTarget, the underlying principle used to call the API must belong to the target environment’s AWS account ID.

After the subscription target has been created for a custom asset type and environment, the environment is eligible as a target for subscription grants.

Subscription grant process

Amazon DataZone emits events based on user actions, and you use this mechanism to trigger the custom authorization process when a subscription grant has been triggered for Amazon MSK topics. Specifically, you use the Subscription grant requested event. These are the steps of the authorization flow:

  1. A Lambda function collects metadata on the following:
    1. Producer Amazon MSK cluster or Kinesis data stream that the consumer is requesting access to. Metadata is collected using the GetListing API.
    2. Metadata about the target environment using a call to GetEnvironment API.
    3. Metadata about the subscription target using a call to GetSubscriptionTarget API to collect the consumer roles to grant.
    4. In parallel, Amazon DataZone internal metadata about the status of the subscription grant needs to be updated, and this happens in this step. Depending on the type of action that’s being done (such as GRANT or REVOKE), the status of the subscription grant is updated respectively (for example, GRANT_IN_PROGRESS, REVOKE_IN_PROGRESS).

After the metadata has been collected, it’s passed downstream as part of the AWS Step Functions state.

  1. Update the resource policy of the target resource (for example, Amazon MSK cluster or Kinesis data stream) in the producer account. The update allows authorized principals from the consumer to access or read the target resource. Example of the policy is as follows:
{
    "Effect": "Allow",
    "Principal": {
        "AWS": [
            "<CONSUMER_ROLES_ARN>"
        ]
    },
    "Action": [
        'kafka-cluster:Connect',
        'kafka-cluster:DescribeTopic',
        'kafka-cluster:DescribeGroup',
        'kafka-cluster:AlterGroup',
        'kafka-cluster:ReadData',
        "kafka:CreateVpcConnection",
        "kafka:GetBootstrapBrokers",
        "kafka:DescribeCluster",
        "kafka:DescribeClusterV2"
    ],
    "Resource": [
        "<CLUSTER_ARN>",
        "<TOPIC_ARN>",
        "<GROUP_ARN>"
    ]
}
  1. Update the configured authorized principals by attaching additional IAM permissions depending on specific scenarios. The following examples illustrate what’s being added.

The base access or read permissions are as follows:

{
    "Effect": "Allow",
    "Action": [
        'kafka-cluster:Connect',
        'kafka-cluster:DescribeTopic',
        'kafka-cluster:DescribeGroup',
        'kafka-cluster:AlterGroup',
        'kafka-cluster:ReadData'
    ],
    "Resource": [
        "<CLUSTER_ARN>",
        "<TOPIC_ARN>",
        "<GROUP_ARN>"
    ]
}

If there’s an AWS Glue Schema registry ARN provided as part of the AWS CDK construct parameter, then additional permissions are added to allow access to both the registry and the specific schema:

{
    "Effect": "Allow",
    "Action": [
        "glue:GetRegistry",
        "glue:ListRegistries",
        "glue:GetSchema",
        "glue:ListSchemas",
        "glue:GetSchemaByDefinition",
        "glue:GetSchemaVersion",
        "glue:ListSchemaVersions",
        "glue:GetSchemaVersionsDiff",
        "glue:CheckSchemaVersionValidity",
        "glue:QuerySchemaVersionMetadata",
        "glue:GetTags"
    ],
    "Resource": [
        "<REGISTRY_ARN>",
        "<SCHEMA_ARN>"
    ]
}

If this grant is for a consumer in a different account, the following permissions are also added to allow managed VPC connections to be created by the consumer:

{
    "Effect": "Allow",
    "Action": [
        "kafka:CreateVpcConnection",
        "ec2:CreateTags",
        "ec2:CreateVPCEndpoint"
    ],
    "Resource": "*"
}
  1. Update the Amazon DataZone internal metadata on the progress of the subscription grant (for example, GRANTED or REVOKED). If there’s an exception in a step, it’s handled inside Step Functions and the subscription grant metadata is updated with a failed state (for example, GRANT_FAILED or REVOKE_FAILED).

Because Amazon DataZone supports multi-account architecture, the subscription grant process is a distributed workflow that needs to perform actions across different accounts, and it’s orchestrated from the Amazon DataZone domain account where all the events are received.

Implement streaming governance in Amazon DataZone with DSF

In this section, we deploy an example to illustrate the solution using DSF on AWS, which provides all the required components to accelerate the implementation of the solution. We use the following CDK L3 constructs from DSF:

  • DataZoneMskAssetType creates the custom asset type representing an Amazon MSK topic in Amazon DataZone
  • DataZoneGsrMskDataSource automatically creates Amazon MSK topic assets in Amazon DataZone based on schema definitions in the Schema registry
  • DataZoneMskCentralAuthorizer and DataZoneMskEnvironmentAuthorizer implement the subscription grant process for Amazon MSK topics and IAM authentication

The following diagram is the architecture for the solution.

Overall solution

In this example, we use Python for the example code. DSF also supports TypeScript.

Deployment steps

Follow the steps in the data-solutions-framework-on-aws README to deploy the solution. You need to deploy the CDK stack first, then create the custom environment and redeploy the stack with additional information.

Verify the example is working

To verify the example is working, produce sample data using the Lambda function StreamingGovernanceStack-ProducerLambda. Follow these steps:

  1. Use the AWS Lambda console to test the Lambda function by running a sample test event. The event JSON should be empty. Save your test event and click Test.

AWS Lambda run test

  1. Producing test events will generate a new schema producer-data-product in the Schema registry. Check the schema is created from the AWS Glue console using the Data Catalog menu from the left and selecting Stream schema registries.

AWS Glue schema registry

  1. New data assets should be in the Amazon DataZone portal, under the PRODUCER project
  2. On the DATA tab, in the left navigation pane, select Inventory data, as shown in the following screenshot
  3. Select producer-data-product

Streaming data product

  1. Select the BUSINESS METADATA tab to view the business metadata, as shown in the following screenshot.

business metadata

  1. To view the schema, select the SCHEMA tab, as shown in the following screenshot

data product schema

  1. To view the lineage, select the LINEAGE tab
  2. To publish the asset, select PUBLISH ASSET, as shown in the following screenshot

asset publication 

Subscribe

To subscribe, follow these steps:

  1. Switch to the consumer project by selecting CONSUMER in the top left of the screen
  2. Select Browse Catalog
  3. Choose producer-data-product and choose SUBSCRIBE, as shown in the following screenshot

subscription

  1. Return to the PRODUCER project and choose producer-data-product, as shown in the following screenshot

subscription grant

  1. Choose APPROVE, as shown in the following screenshot

subscription grant approval

  1. Go to the AWS Identity and Access Management (IAM) console and search for the consumer role. In the role definition, you should see an IAM inline policy with permissions on the Amazon MSK cluster, the Kafka topic, the Kafka consumer group, the AWS Glue schema registry and the schema from the producer.

IAM consumer policy

  1. Now let’s switch to the consumer’s environment in the Amazon Managed Service for Apache Flink console and run the Flink application called flink-consumer using the Run button.

Flink consumer

  1. Go back to the Amazon DataZone portal, and confirm that the lineage under the CONSUMER project was updated and the new Flink job run node was added to the lineage graph, as shown in the following screenshot

lineage

Clean up

To clean up the resources you created as part of this walkthrough, follow these steps:

  1. Stop the Amazon Managed Streaming for Apache Flink job.
  2. Revoke the subscription grant from the Amazon DataZone console.
  3. Run cdk destroy in your local terminal to delete the stack. Because you marked the constructs with a RemovalPolicy.DESTROY and configured DSF to remove data on destroy, running cdk destroy or deleting the stack from the AWS CloudFormation console will clean up the provisioned resources.

Conclusion

In this post, we shared how you can integrate streaming data from Amazon MSK within Amazon DataZone to create a unified data governance framework that spans the entire data lifecycle, from the ingestion of streaming data to its storage and eventual consumption by diverse producers and consumers.

We also demonstrated how to use the AWS CDK and the DSF on AWS to quickly implement this solution using built-in best practices. In addition to the Amazon DataZone streaming governance, DSF supports other patterns, such as Spark data processing and Amazon Redshift data warehousing. Our roadmap is publicly available, and we look forward to your feature requests, contributions, and feedback. You can get started using DSF by following our Quick start guide.


About the Authors

Vincent GromakowskiVincent Gromakowski is a Principal Analytics Solutions Architect at AWS where he enjoys solving customers’ data challenges. He uses his strong expertise on analytics, distributed systems and resource orchestration platform to be a trusted technical advisor for AWS customers.

Francisco MorilloFrancisco Morillo is a Sr. Streaming Solutions Architect at AWS, specializing in real-time analytics architectures. With over five years in the streaming data space, Francisco has worked as a data analyst for startups and as a big data engineer for consultancies, building streaming data pipelines. He has deep expertise in Amazon Managed Streaming for Apache Kafka (Amazon MSK) and Amazon Managed Service for Apache Flink. Francisco collaborates closely with AWS customers to build scalable streaming data solutions and advanced streaming data lakes, ensuring seamless data processing and real-time insights.

Jan Michael Go TanJan Michael Go Tan is a Principal Solutions Architect for Amazon Web Services. He helps customers design scalable and innovative solutions with the AWS Cloud.

Sofia ZilbermanSofia Zilberman is a Sr. Analytics Specialist Solutions Architect at Amazon Web Services. She has a track record of 15 years of creating large-scale, distributed processing systems. She remains passionate about big data technologies and architecture trends, and is constantly on the lookout for functional and technological innovations.

Four ways to grant cross-account access in AWS

Post Syndicated from Anshu Bathla original https://aws.amazon.com/blogs/security/four-ways-to-grant-cross-account-access-in-aws/

As your Amazon Web Services (AWS) environment grows, you might develop a need to grant cross-account access to resources. This could be for various reasons, such as enabling centralized operations across multiple AWS accounts, sharing resources across teams or projects within your organization, or integrating with third-party services. However, granting cross-account access requires careful consideration of your security, availability, and manageability requirements.

In this blog post, we explore four different ways to grant cross-account access using resource-based policies. Each method has its own unique tradeoffs, and the best choice depends on your specific requirements and use case.

Evaluating different techniques for granting cross-account access

Cross-account access is granted by identity-based policies and resource-based policies in AWS Identity and Access Management (IAM). Identity-based policies attach to an IAM role, while resource-based polices attach to resources like Amazon Simple Storage Service (Amazon S3) buckets and AWS Key Management Service (AWS KMS) keys. Resource-based policies require you to specify one or more principals (IAM users or roles) that are allowed to access the resource.

Your choice of how to specify the principal in a resource-based policy impacts some aspects of both the confidentiality and the availability of your solution. Understanding this impact and making the right tradeoffs for your use case is the focus of this post.

An example scenario

Imagine that you have an S3 bucket in your AWS account (Account A) that needs to be accessed by different principals in another AWS account (Account B). For this scenario, we assume that the principals in Account B have the necessary access to S3 in their identity-based policies, and we will focus on authoring the resource-based policies in Account A. While the methods explained here use Amazon S3, the concepts discussed apply to all AWS services that support resource-based policies. In the following sections, we walk through four different ways to grant cross-account access in this scenario and discuss the tradeoffs of each.

Method 1: Grant access to a specific IAM role using the Principal element of the resource-based policy

In this example, you use an S3 bucket policy to grant access to a specific IAM role (RoleFromAccountB) in Account B by specifying the IAM role’s Amazon Resource Name (ARN) in the Principal element of the policy in Account A.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "AllowRoleInThePrincipalElement",
      "Principal": {
        "AWS": "arn:aws:iam::111122223333:role/RoleFromAccountB"
      },
      "Effect": "Allow",
      "Action": "s3:GetObject",
      "Resource": "arn:aws:s3:::amzn-s3-demo-bucket-account-a/*"
    }
  ]
}

Using this bucket policy, if someone in Account B deletes or recreates the role (RoleFromAccountB), then that role can no longer access the amzn-s3-demo-bucket-account-a bucket, even if that role is recreated with the same name. The reason is that when you save this policy, the role ARN is mapped to the unique ID of the role, which looks something like this: AROADBQP57FF2AEXAMPLE. You will see a role identifier in the Principal element of your resource-based policies if you view them after you delete the role that they referenced.

This behavior is intentional. The resource-based policy only allows the specific instance of the role that you set as principal at the time of policy creation. This helps prevent unintended access to your resources if you delete a role, but forget to update your resource-based policy to remove that role. This behavior can also cause an availability risk because the role (RoleFromAccountB) will have a new unique ID when it is recreated and will no longer have access to the bucket. Roles can be recreated for a number of reasons, including accidentally when you use tools such as infrastructure as code.

You might consider choosing this method if:

  • You own the roles in both Account A and Account B and can control the creation and deletion of these roles.
  • You want your resource-based policy in Account A to stop granting access when the specified role (RoleFromAccountB) is deleted.
  • You prioritize granular access control over potential availability concerns if the role (RoleFromAccountB) is deleted.

Method 2: Grant access to an account using the Principal element of the resource-based policy

In this example, you grant access to a specific account in the Principal element of the resource-based policy. This resource-based policy of Account A allows any user or role from Account B that also has an identity-based policy that grants them access to read the objects.

Note: You can use either "Principal": {"AWS": "111122223333"} or "Principal": {"AWS": "arn:aws:iam::111122223333:root"} in the Principal element. They are equivalent, and the long-form ARN does not represent the root user.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "AllowAccountInThePrincipalElement",
      "Principal": {
        "AWS": "111122223333"
      },
      "Effect": "Allow",
      "Action": "s3:GetObject",
      "Resource": "arn:aws:s3:::amzn-s3-demo-bucket-account-a/*"
    }
  ]
}

This resource-based policy helps avoid the potential availability issue discussed for Method 1. If a role in Account B that needs to have access to the bucket is recreated, it will still have access after the recreation of that role. This is because you don’t specify a role in the Principal element—instead, you specify an account. If you use Method 2, you must be comfortable delegating access control decisions to the owner of that account.

This approach explicitly delegates access control decisions to IAM in the other account (Account B). Principals in Account B have access to this bucket if allowed by their identity-based policies.

You might consider choosing this method if:

  • You need to grant access to many principals in Account B.
  • You want to delegate the access decision in the account where the principal exists (Account B).
  • You prioritize ease of management and availability over granular access control.

Method 3: Grant access to a specific IAM role using the aws:PrincipalArn condition

This method expands on Method 2 and adds a condition that grants access only to a specific IAM role. Similar to Method 2, you use the account number as the value of the Principal element, but also use the aws:PrincipalArn condition key to limit access to a specific principal in Account B.

The aws:PrincipalArn condition key is a global condition key that compares the ARN of the principal that made the request with the ARN that you specify in the policy. For IAM roles, the request context returns the ARN of the role, not the ARN of the user that assumed the role.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "AllowAccountInPrincipalAndRoleInPrincipalArn",
      "Principal": {
        "AWS": "111122223333"
      },
      "Effect": "Allow",
      "Action": "s3:GetObject",
      "Resource": "arn:aws:s3:::amzn-s3-demo-bucket-account-a/*",
      "Condition": {
        "ArnEquals": {
          "aws:PrincipalArn": "arn:aws:iam::111122223333:role/RoleFromAccountB"
        }
      }
    }
  ]
}

This policy comes with the same availability benefits as the policy in Method 2: access to this resource will survive role recreation. This is because the role is translated to its unique identifier only when it is used in the Principal element. It is not translated to a unique identifier when it is used in a condition. If the role (RoleFromAccountB) in Account B is recreated, accidentally or intentionally, the policy will continue to grant access because the role matches the role ARN specified in the condition key of the resource-based policy in Account A. As a result, Method 3 provides a balanced approach to availability and security.

You might consider choosing this method if:

  • You are comfortable that this policy will continue to grant access to the role specified in the aws:PrincipalArn condition key if that role (RoleFromAccountB) is recreated.
  • You don’t own the Account B you are granting access to and don’t control when that role may be recreated.
  • You want a balance of availability and confidentiality.

Method 4: Grant access to an entire AWS Organizations organization

This method is focused on a different use case and is not an alternative to the methods listed earlier. Use this method if you have a resource (an S3 bucket, in this example) that you want to share with your entire organization, but not share with anyone outside of it.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "AllowAccessToAnEntireOrganization",
      "Principal": {
        "AWS": "*"
      },
      "Effect": "Allow",
      "Action": "s3:GetObject",
      "Resource": "arn:aws:s3:::amzn-s3-demo-bucket-account-a/*",
      "Condition": {
        "StringEquals": {
          "aws:PrincipalOrgId": "o-12345"
        },
        "StringNotEquals": {
          "aws:PrincipalAccount": "${aws:ResourceAccount}"
        }
      }
    }
  ]
}

There is no way to specify an organization by using the Principal element of a resource-based policy, so you must use the aws:PrincipalOrgId condition key to restrict access to a specific organization. In this policy, you specify a wildcard in the Principal element, which says that anyone can access the bucket. Then the condition reduces “anyone” to just those AWS account principals that belong to the specified organization and have an identity-based policy that allows them access.

You then add an additional conditional block that compares the aws:PrincipalAccount condition key to the aws:ResourceAccount condition key by using a policy variable. This extra conditional block is optional and excludes the account that owns the bucket (Account A) from the allow statement. The reason for using this extra conditional block is so that principals in Account A still require an allow statement in their identity-based policy to access this bucket. If you choose to exclude this aws:PrincipalAccount comparison, principals in Account A are granted access to the bucket without an explicit allow statement in their identity-based policy. Policy evaluation logic only requires either the identity-based policy or the resource-based policy (but not both) to allow a request when the principal and resource are in the same account.

You might consider choosing this method if:

  • You have a shared resource that should be accessible to your entire organization.

Conclusion

Choosing a method to grant cross-account access requires careful consideration of your requirements and use case. Each of the four methods discussed in this blog post has its own advantages and tradeoffs. By understanding these methods and their implications, you can decide on the most appropriate approach to grant cross-account access to your AWS resources. Remember to regularly review and audit your resource-based policies to verify that they align with your security and access requirements.

To learn how resource-based policies work with Amazon S3, see the blog post IAM Policies and Bucket Policies and ACLs! Oh My! Controlling Access to S3 Resources.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
 

Anshu Bathla
Anshu Bathla

Anshu is a Lead Consultant – SRC at AWS, based in Gurugram, India. He works with customers across diverse verticals to help strengthen their security infrastructure and achieve their security goals. Outside of work, Anshu enjoys reading books and gardening at his home garden.
Jay Goradia
Jay Goradia

Jay is a Technical Account Manager (TAM) at AWS who works closely with enterprise customers to accelerate their cloud journey through strategic guidance and technical expertise. Using his security background, he helps organizations understand security best practices in AWS.

Improving Security in Amazon WorkMail with MFA

Post Syndicated from Zip Zieper original https://aws.amazon.com/blogs/messaging-and-targeting/improving-security-in-amazon-workmail-with-mfa/

Securing your business email is more critical than ever in today’s digital workplace. To help you protect your users and data in Amazon WorkMail, we have introduced enhanced security features that give organizations more control and protection for their communication platforms. With the integration of AWS Identity and Access Management (IAM) Identity Center, WorkMail now offers robust multi-factor authentication and personal access token capabilities that can help prevent unauthorized access to user accounts and protect sensitive business communications. In this post, we’ll explore how these new security features can strengthen your organization’s email security strategy

Introduction

Email remains a critical business communication channel, yet it’s also one of the most targeted by cybercriminals. When you’re managing an organization’s communications, a single compromised account can lead to significant financial losses, damage your reputation, and serve as a gateway for additional cyber attacks. Traditional username and password protection is no longer adequate against growing cyber threats.

With Amazon WorkMail, you now have powerful tools to enhance your email security. Our support for Multi-Factor Authentication (MFA) and Personal Access Token (PAT) capabilities provides administrators with essential additional security layers to prevent unauthorized account access.

This blog demonstrates WorkMail’s integration with the IAM Identity Center’s default identity store to enable these advanced security features. If you’re using third-party identity providers like Microsoft Entra ID or Okta Universal Directory, you’ll find dedicated integration guides in our documentation.

High-level Overview

Amazon WorkMail’s default authentication is established via a unique username & password:

  1. Users of the WorkMail web-app sign in using their username and password.
  2. Users who access WorkMail from a desktop &/or mobile email application sign in using their username and password.WorkMail standard login

After you integrate WorkMail with IAM Identity Center, Amazon WorkMail can be configured with enhanced authentication that requires:

  1. Users of the WorkMail web-app will log-in via their unique AWS Access Portal using username, password and a MFA token. Upon successful log-in, they select and are redirected into the WorkMail web-app.
  2. Users who access WorkMail from a desktop &/or mobile email app continue to sign in to WorkMail using their username, however they must use a personal access token (PAT) instead of their WorkMail password.

WorkMail via MFA or PAT

More details about WorkMail authentication can be found in our documentation.

Prerequisites

  1. Administrator access to an AWS account
    1. You can evaluate the integration in this post for a limited period of time using an AWS Free Tier Account (link = https://aws.amazon.com/free )
  2. Administrator access to an Amazon WorkMail Organization
    1. Your WorkMail organization should have at least 3 or more users for testing
  3. Administrator access to Amazon IAM Identity Center
  4. Your WorkMail and IAM Identity Center must be in the same AWS region

High-level Configuration Steps

  1. Configure Identity Center (see our documentation for detailed information).
  2. Configure WorkMail to use Identity Center (see our documentation for detailed information).
  3. Assign IAM Identity Center users/groups to WorkMail organization
    1. Associate Amazon WorkMail users with IAM Identity Center users (this step is not necessary if your IdC and WorkMail user names are exactly the same, see our documentation for details)
  4. Check Authentication mode (see documentation) & Personal access token configuration (see documentation).
    1. Allow both WorkMail Directory (no MFA/PAT) and Identity Center (requires MFA & PAT) modes for testing.
  5. Test your users’ access to WorkMail with MFA & PAT
  6. Notify your WorkMail users of upcoming changes to login procedures.
  7. Switch WorkMail Authentication Mode to Identity Center only.
    1. When your users are ready for MFA and PAT, switch authentication mode to require MFA and desktop and mobile email clients to use PAT.
  8. Review additional WorkMail security guidance in AWS blogs and documentation to ensure you are up to date with the latest security guidance.

Detailed Configuration Guidance

Configure AWS IAM Identity Center

    1. Open the IdC console in the same AWS region as your WorkMail organization.
      1. If this is your first time accessing IAM Identity Center, you’ll be greeted with the IdC console home page and “Enable IAM Identity Center”. Click the **`Enable`** button.
      2. Enable IAM Identity Center
      3. Unless you have a reason to use an account instance of IdC, choose Enable.
      4. Org instance of IdC
      5. In a new browser window, open the WorkMail console in the same AWS region as the IdC you created above.
      6. Arrange the IdC console browser next to the WorkMail console browser window so you can easily copy/paste between the two services.
      7. Sync IdC and WorkMail users
      8. In the IdC console’s left navigation rail, choose users and click add user.
        1. Create several IdC user accounts with the same usernames and email addresses as your WorkMail users.
          1. Using identical usernames in Amazon WorkMail and IAM Identity Center simplifies user synchronization and reduces authentication errors during integration. This alignment streamlines troubleshooting and user lifecycle management while ensuring consistent access control across both services.)
        2. Make sure the “Send an email to this user with password setup instructions.” is selected.
          1. The user will receive an email with a link to set up a password and instructions to connect to the AWS access portal. The link will be valid for up to 7 days. You can grant this user permissions to accounts or applications (such as WorkMail) when they sign in to the AWS access portal.
          2. join-idc-email
      9. In IdC’s left navigation rail, choose groups and create a new group called “workmail_users”.
        1. IdC-workmail-users-group
        2. Add the IdC users created above to the IdC workmail_users group.
  1. Configure WorkMail to use Identity Center
    1. In the WorkMail console’s left navigation rail, click the link for Identity Center.
    2. Click the down arrow for Multi-factor authentication setup guide
    3. Click Step 1 – Enable identity center and click Enable.
    4. enable-MFA-workmail.
  2. Assign IAM Identity Center users/groups to WorkMail organization
    1. Click the down arrow for Multi-factor authentication setup guide
    2. Click Step 2 – Add and Assign users and click Next
    3. add-assign-users
    4. Assigning users and groups – Users and groups synced to your Identity Center directory are available to assign to your application. Learn more
      1. Click Get Started 
      2. Type workmail_users and select it from the drop-down list.
      3. assign-group
      4. Click Assign
        1. You will get a message “Successfully assigned group workmail_users. Please continue with step 3 by associating users within this group with WorkMail users.”
  3. Authentication mode & Personal access token configuration
    1. The default Authentication mode is set to WorkMail directory and Identity center. Don’t change this yet.
      1. This will allow WorkMail web-app users to continue to login to the WorkMail client directly, without MFA.
    2. The Personal access token configuration default is set to active, and token lifespan set to 365 days. PATs are used by desktop and mobile email clients to login to WorkMail.
      1. This will allow desktop and mobile email clients to continue to login to the WorkMail with their username and password, without a PAT.
  4. Test WorkMail logins to verify a few users can properly access their WorkMail accounts via both the WorkMail web-app and your organization’s unique AWS access portal URL.
    1. Open the Amazon WorkMail web application and login as one of your test users.
      1. You should have an email invitation to join AWS IAM Identity Center.
      2. Accept the invitation.
      3. Create a IdC password.
      4. Use your username and the new password to login to IdC.
      5. Register an MFA device
      6. enable-mfa
      7. Click Next
      8. You’ll be redirected to the AWS access portal.
        1. Enter your user name and password
        2. Provide your MFA token
      9. Click the tile for Amazon WorkMail to login to the WorkMail web-app
    2. Desktop or mobile email software users need to create PATs to access WorkMail (once the WorkMail administrator disables the WorkMail directory Authentication mode and logins are via the Identity center AWS access portal URL only). Note – PATs are retrieved by individual users from within the WorkMail web-client after logging in via the AWS access portal URL (with MFA).
      1. Open the AWS access portal URL and login
        1. You can find the URL from the Identity Center console > Settings > AWS access portal URL
      2. Login via your username password
      3. Register an MFA device
      4. You’ll be redirected to the AWS access portal.
        1. Enter your user name and password
        2. Provide your MFA token
      5. Click the tile for Amazon WorkMail to login to the WorkMail web-app
      6. In the web-app, click the settings (gear in top right) icon
      7. get-PAT
        1. In settings, click Personal access token and Create token
        2. Enter a token name (typically the device on which you’ll use this PAT) and select create token.
        3. Copy the token value (this is the only time you can retrieve this token value).
        4. Open your desktop or mobile email software, enter your username and your PAT (the PAT replaces your existing user password).
        5. update-email-app-with-pat
  5. Notify your WorkMail users of upcoming changes to login procedures
    1. Once you have tested the integration between Amazon WorkMail and IAM Identity Center with a few test users, you should prepare your WorkMail users for the increased login security. For example, you could send them an email that explains:
      1. The organization is adding an additional login security step to help protect their inboxes.
      2. Inform them that they should anticipate an email from the AWS IAM Identity Center with info about the upcoming implementation of MFA for web-app users and PATs for desktop and mobile client users.
      3. Users should accept the invitation and create a new password for the AWS IAM Identity Center.
      4. Inform them that once WorkMail MFA is enabled, all WorkMail web-app users will be required to use their username, password and MFA.
      5. Inform them that once WorkMail PATs are enabled, all WorkMail desktop and mobile email client users will need to login to the WorkMail web client (with MFA) via the AWS access portal URL, create one PAT per software client (the same PAT can not be used on desktop and mobile). They then must update their desktop or mobile email software to use their username and PAT, instead of their current password. Explain that the PAT is now their email client application password and their personal desktop or mobile email software passwords will no longer work.
      6. Provide users with a way to request support.
  6. Switch WorkMail Authentication Mode to Identity Center only
    1. Once you are satisfied that your WorkMail users have incorporated MFA and/or PATs into their WorkMail login routines, the WorkMail administrator should disable the WorkMail directory Authentication mode found in the WorkMail console under Organization > Identity Center.
  7. Review additional guidance to improve WorkMail security via AWS blogs and documentation.
    1. WorkMail Audit Logging Overview: https://aws.amazon.com/blogs/messaging-and-targeting/an-introduction-to-amazon-workmail-audit-logging/
    2. Custom Security Alarm Setup: https://aws.amazon.com/blogs/messaging-and-targeting/how-to-create-a-big-yellow-taxi-to-help-protect-amazon-workmail/
    3. For comprehensive security guidelines, refer to the Amazon WorkMail Security Documentation: https://docs.aws.amazon.com/workmail/latest/adminguide/security.html

Conclusion – Strengthen your Amazon WorkMail security with IAM Identity Center

By integrating Amazon WorkMail with IAM Identity Center you can more fully protect your organization’s email communications. This integration also centralizes user access management, allowing you to:

  • Manage WorkMail access alongside other AWS applications
  • Reduce security risks in a landscape of constant cyber threats
  • Simplify administrative tasks through a single dashboard

To keep your email environment secure, we recommend you:

Take control of your email communications today with Amazon WorkMail

  • Enable IAM Identity Center Integration
  • Connect your WorkMail organization to centralized access management
  • Configure WorkMail to require:
    • Multi-Factor Authentication (MFA) – Adds an extra layer of security for web-app users
    • Personal Access Tokens (PAT) – Add an extra layer of security for desktop and mobile client access
  • Visit the WorkMail Console (https://aws.amazon.com/workmail/) to begin configuration

Need guidance? Contact your AWS account team or check out our technical documentation.

Join the conversation and connect with other administrators and security professionals on the AWS re:Post community to share insights and learn best practices.

AWS CloudFormation: 2024 Year in Review

Post Syndicated from Idriss Laouali Abdou original https://aws.amazon.com/blogs/devops/aws-cloudformation-2024-year-in-review/

AWS CloudFormation: 2024 Year in Review

AWS CloudFormation enables you to model and provision your cloud application infrastructure as code-base templates. Whether you prefer writing templates directly in JSON or YAML, or using programming languages like Python, Java, and TypeScript with the AWS Cloud Development Kit (CDK), CloudFormation and CDK provide the flexibility you need. For organizations adopting multi-account strategies, CloudFormation StackSets offers a powerful capability to deploy resources across multiple regions and accounts in parallel.

Last year, we delivered broad set of enhancements that accelerated the development cycle, simplified troubleshooting, and introduced new deployment safety and configuration governance capabilities. Let’s dive into the key launches that shaped CloudFormation in 2024.

Development cycle improvements

Deploy stacks up to 40% faster with optimistic stabilization and configuration complete

In March, we introduced optimistic stabilization with the new CONFIGURATION_COMPLETE event, delivering up to 40% faster stack creation times. This new event signals that CloudFormation has created the resource and applied the configuration as defined in the stack template, allowing us to begin parallel creation of dependent resources. For example, if your stack contains resource B that depends on resource A, CloudFormation will now start provisioning resource B when resource A reaches the CONFIGURATION_COMPLETE state, rather than waiting for full stabilization. Read How we sped up AWS CloudFormation deployments with optimistic stabilization to learn more.

CloudFormation’s old and new deployment strategy

Figure 1: CloudFormation’s old and new deployment strategy

Catch template errors before deployment with early validation

In March, we launched early resource properties validation checks. This feature validates your stack operation upfront for invalid resource property errors, helping you fail fast and minimize the steps required for a successful deployment. Previously, you had to wait until CloudFormation attempted to provision a resource before discovering property-related errors. Now, we validate your template before deploying the first resource and provide clear error messages upfront.

CloudFormation’s early template properties validation feature

Figure 2: CloudFormation’s early template properties validation feature

Safely clean up failed stacks with enhanced deletion controls

In May, we enhanced the DeleteStack API with a new DeletionMode parameter, allowing you to safely delete stacks that are in DELETE_FAILED state. By passing the FORCE_DELETE_STACK value to this parameter, you can now resolve stuck stacks more efficiently during your development and testing cycles.

Accelerate feedback loops with CloudFormation custom resource timeout controls

In June, we introduced the ServiceTimeout property for custom resources. This new capability allows you to set custom timeout values for your custom resource logic execution. Previously, custom resources had a fixed one-hour timeout, which could lead to long wait times when debugging custom resource logic. Now, you can set appropriate timeout values to accelerate your development feedback loops. Refer to the custom resources documentation to learn more about the ServiceTimeout property.

CloudFormation’s ServiceTimeout property for Custom resource

Figure 3: CloudFormation’s ServiceTimeout property for Custom resource

Streamlined Troubleshooting Experience

Resolve deployment issues faster with one-click CloudTrail access

In May, we launched integration with AWS CloudTrail in the Events tab of the CloudFormation console. Troubleshooting some failed stack operations can be time-consuming, so we have streamlined this process by providing direct links from stack operation events to relevant CloudTrail events. When you click ‘Detect Root Cause’ in the CloudFormation Console, you’ll now see a pre-configured CloudTrail deep-link to the API events generated by your stack operation, eliminating multiple manual steps from the troubleshooting process.

CloudFormation troubleshooting with CloudTrail integrationFigure 4: CloudFormation troubleshooting with CloudTrail integration

Visualize your entire deployment process with timeline view

In November, we launched deployment timeline view. It gives you unprecedented visibility into your stack operations. This visual tool shows the sequence of actions CloudFormation takes during a deployment, helping you understand resource dependencies and provisioning duration. You can see which resources are being created in parallel, track their status through color-coding, and quickly identify bottlenecks in your deployments.

CloudFormation’s deployment timeline view

Figure 5: CloudFormation’s deployment timeline view

Get instant troubleshooting help with Amazon Q Developer

We integrated Amazon Q Developer to provide AI-powered assistance for troubleshooting. When you encounter a failed stack operation, you can now click “Diagnose with Q” to receive a clear, human-readable analysis of the error. Need more help? The “Help me resolve” button provides actionable steps tailored to your specific scenario.

CloudFormation troubleshooting with Q featureFigure 6: CloudFormation troubleshooting with Q feature

Enhanced Deployment Safety

In April, we improved change sets to help you better understand the impact of your stack operations. Change sets now show detailed before-and-after values of resource properties and attributes, such as deletion policies. This enhancement helps you detect unintended resource property-level changes, such as a Lambda MemorySize or Runtime values change, during your change sets reviews.

We’ve also improved how change sets handle references. When referenced values are available before deployment, Change sets can now resolve them to their expected values, giving you a more accurate preview of your planned changes.

CloudFormation’s change sets feature

Figure 7: CloudFormation’s change sets feature

Easy onboarding to Infrastructure-as-Code (IaC)

Eliminate weeks of manual effort with IaC Generator

In February, we launched the CloudFormation IaC Generator, a capability addressing one of our customers’ biggest challenges: onboarding existing cloud resources to CloudFormation. This feature makes it easier to generate CloudFormation templates for existing AWS resources. You can now onboard workloads to IaC in minutes instead of spending weeks writing templates manually.

The IaC generator supports over 600 AWS resource types and provides recommendations for related resources. For instance, when you select an S3 bucket, it automatically suggests including associated bucket policies. You can use the generated templates to import resources into CloudFormation, download them for deployment.

CloudFormation’s IaC Generator

Figure 8: CloudFormation’s IaC Generator

In August, we enhanced the IaC Generator with two improvements. First, we added a graphical summary view that helps you quickly find resources after the account scan completes. Second, we integrated with AWS Infrastructure Composer to visualize your application architecture, making it easier to understand resource relationships and configurations.

IaC generator resource scanFigure 9: IaC generator resource scan

Proactive Control Improvements

In November, we launched major enhancements to CloudFormation Hooks, giving you easier ways to author proactive configuration controls and more points to enforce them with your cloud infrastructure provisioning.

CloudFormation Hooks for stack and change set target invocation points

First, we introduced stack and change set target invocation points for CloudFormation Hooks. This extends Hooks beyond individual resource validation, allowing you to run validation checks against entire templates and examine resource relationships. For example, you can now create hooks that validate architectural patterns across multiple resources or enforce team-specific deployment standards. With the change set invocation point, you can automate your change set reviews and reduce the time needed to resolve compliance issues. Refer to the Hooks developer guide to learn more.

CloudFormation’s Hooks for stack and change set target invocation points
Figure 10: CloudFormation’s Hooks for stack and change set target invocation points

Managed hooks for the CloudFormation Guard domain specific language

We introduced the managed hooks to author configuration controls using CloudFormation Guard domain-specific language. This simplifies the hook creation process—you can now write hooks by providing your Guard rule set stored as an S3 object. This is particularly valuable if you’re already using Guard for static template validation, as you can extend these rules to dynamic checks before deployments. To learn more about the Guard hook, check out the AWS DevOps Blog or refer to the Guard Hook User Guide.

CloudFormation Hooks’ Guard language feature

Figure 11: CloudFormation Hooks’ Guard language feature

Managed hooks for AWS Lambda functions

For extended flexibility, we also introduced the managed hooks to implement configuration controls using Lambda function. You can now simply point to a Lambda function with the Lambda Amazon Resource Names (ARNs) for Hooks to invoke. To learn more about the Lambda hook, check out the AWS DevOps Blog or refer to the Lambda Hooks User Guide.

CloudFormation Hooks’ Lambda function featureFigure 12: CloudFormation Hooks’ Lambda function feature

CloudFormation Hooks for AWS Cloud Control API target invocation points

Lastly, we extended Hooks to support AWS Cloud Control API (CCAPI) resource configurations. This means your existing resource Hooks can now evaluate configurations from CCAPI create and update operations, allowing you to standardize your proactive control evaluation regardless your IaC tool. If you’re already using pre-built Lambda or Guard hooks, you simply need to specify “Cloud_Control” as a target in your hooks’ configuration to extend their coverage. Learn the detail of this feature from this AWS DevOps Blog.
CloudFormation Hooks for AWS Cloud Control API target invocation point
Figure 13: CloudFormation Hooks for AWS Cloud Control API target invocation point

Additional Platform Improvements

StackSets ListStackSetAutoDeploymentTargets API

In March, we enhanced StackSets with the ListStackSetAutoDeploymentTargets API. This new capability gives you better visibility into your auto-deployment configurations by allowing you to list existing target Organizational Units (OUs) and AWS Regions for a given stack set. Instead of logging into individual accounts to understand your deployment scope, you can now get this information in a single API call.

CloudFormation Git sync with request review support

In September, we improved CloudFormation Git sync with pull request workflow support. When you create or update a pull request in a linked repository, CloudFormation automatically posts change set information as PR comments. This integration provides a clear overview of proposed changes within your familiar Git workflow, allowing team members to review infrastructure changes alongside code changes. Visit our user guide and launch blog to learn more.

CloudFormation Git sync with request review support feature Figure 14: CloudFormation Git sync with request review support feature

Early 2025 improvements

Reshape your AWS CloudFormation stacks seamlessly with stack refactoring

In February 2025, CloudFormation introduced a new capability called stack refactoring that makes it easy to reorganize cloud resources across your CloudFormation stacks. Stack refactoring enables you to move resources from one stack to another, split monolithic stacks into smaller components, and rename the logical name of resources within a stack. This enables you to adapt your stacks to meet architectural patterns, operational needs, or business requirements. To explore an example scenario, read Introducing AWS CloudFormation Stack Refactoring.

Learn more

Here are some resources to help you get started learning and using CloudFormation to manage your cloud infrastructure:

Conclusion

As we are starting 2025, our focus remains on making infrastructure deployment faster, safer, and more manageable. These enhancements reflect our commitment to solving real customer challenges and improving the CloudFormation experience. We are excited about the roadmap ahead and look forward to bringing you more innovations in 2025.

We encourage you to try these new features and share your feedback. For more detailed information about any of these launches, visit our documentation or check out the AWS DevOps Blog.

About the author:

Idriss Laouali Abdou

Idriss is a Senior Product Manager at AWS, focused on delivering the best experience for AWS Infrastructure as Code (IaC) customers. When not at work, he dedicates his time to creating educational content that helps thousands of students, and enjoys cooking and exploring new places.

Streamline Development with New Amazon Q Developer Agents

Post Syndicated from Ryan Yanchuleff original https://aws.amazon.com/blogs/devops/streamline-development-with-new-amazon-q-developer-agents/

As software development continues to evolve at a rapid pace, developers are constantly seeking tools that can streamline their workflow, improve code quality, and boost productivity. Amazon Web Services (AWS) has answered this call with the introduction of powerful new AI agents for Amazon Q Developer.

AI-powered agents transform the way developers approach documentation, unit testing, and code reviews. Agents are autonomous software programs that can interact with their environment, gather data, and use that data to perform tasks independently to achieve pre-defined goals. They are rational, making informed decisions based on their perceptions and data to optimize performance. AI agents can bring benefits like improved productivity, reduced costs, better decision-making, and enhanced customer experience. Amazon Q Developer has three new agents: /doc, /test, and /review. In this post, we’ll explore each of them in a bit more detail and talk about how you can incorporate them into your daily development workflow.

The first agent released for Amazon Q Developer was the software developer agent launched last year. The /dev agent allows you to generate new code or make code changes directly within your IDE to implement new features or fix issues in your projects. Simply provide a description of the task you want to accomplish, and Q Developer will analyze select context from your current codebase to generate the necessary code changes. Q Developer can help you build new AWS applications or update existing ones, providing a step-by-step summary of the changes it’s making and allowing you to easily accept or reject the proposed modifications. Q Developer has the ability to handle everything from creating new API endpoints to optimizing database queries, the /dev feature is a must-try tool for any developer working on anything from simple to complex tasks.

In the coming sections, let’s dive into how we can put these new agents to use with an application use case.

Prerequisites

To begin using Amazon Q Developer, the following are required:

Note: Amazon Q Developer supports additional IDEs such as Eclipse and Visual Studio Pro, but only the those listed above have agent support enabled.

Application Overview

You are a software engineer at a technology firm and have been tasked to develop documentation, integrate unit tests and enhance security posture of the application shown below. The application uses serverless architecture with Amazon API Gateway, AWS Lambda and Amazon DynamoDB services and implements RESTful APIs in Python.

Simple architectural diagram demonstrating the use of Amazon API Gateway, Amazon DynamoDB, and multiple AWS Lambda functions to service the routes.

We have learned that Q Developer’s new documentation, test, and security scanning agents can assist with the application software development lifecycle (SDLC). SDLC is a flywheel with several stages such as Planning and Research, Coding, Documentation, Testing, Build and Deploy, Operations and Maintenance.

With the new Q Developer agents, let’s see how we can put these into practice with the above application as part of the SDLC.

Documentation Generation (/doc)

Creating and maintaining application documentation is often one of the most time-consuming and frequently overlooked aspects of software development. Detailed documentation empowers team members and stakeholders about code, design, and architecture. It enhances readability, facilitates rapid onboarding to accelerate new feature and functionality development and streamlines SDLC tasks. The introduction of the /doc agent in Amazon Q Developer makes this process both easier and faster. Amazon Q Developer can now automatically generate new README files at any level of your project by analyzing the code in your selected folder or review code changes and recommend corresponding updates to existing documentation. Additionally, developers can leverage natural language to request specific modifications to their files to include custom summarizations, making the entire process more intuitive and user-friendly. These capabilities help reduce the burden on development teams while maintaining accurate and up-to-date project documentation as teams operate the applications.

The above application doesn’t have a detailed README and the following example shows how you can leverage /doc agent of Q Developer in Visual Studio Code (VS Code) IDE to help generate detailed documentation for the application codebase.

Prompt:

/doc Create a README

Short animation of the /doc agent creating a README document

Best practices when using Q Developer /doc agent:

  • For large repositories, consider requesting documentation by targeting specific directories for documentation.
  • Maintain well-commented and organized code with good naming conventions to improve the quality of generated documentation.
  • Be specific when describing desired changes to your README.

Note: The /doc feature supports various file types, including .template files, requirements.txt, package.json, tsconfig.json, Dockerfile, and more. It’s important to note that there are quotas in place, such as a maximum existing README size of 15 KB and a code project size limit of 200 MB uncompressed or 50 MB compressed.

Unit Test Generation (/test)

Test driven development is a common SDLC best practice. Part of it is Unit testing, which is a cornerstone for maintaining code quality. Unit testing helps catch bugs early on and minimize tech debt. However, the process of writing comprehensive tests has traditionally demanded significant time and effort from development teams. The new /test agent in Amazon Q Developer is a groundbreaking solution that automates the testing process and enables developers to channel more energy into feature development and problem solving. The tool comes equipped with several powerful capabilities that streamline the testing workflow. It automatically identifies necessary test cases, generates appropriate mocks and stubs for isolated testing scenarios, and produces test code based on the identified cases. Currently supporting both Java and Python projects, the feature seamlessly integrates with popular development environments including VS Code and JetBrains IDEs, making it an invaluable asset for modern development teams looking to enhance their testing practices while maximizing productivity.

With the new Q Developer /test agent, you can generate unit tests by specifying section of code such as class, function or method and also highlight code to generate tests within the IDE. In the following example, you can see the use of /test agent to generate unit tests for open Python file (add_item.py) that adds new items to the DynamoDB table.

Prompt:

/test generate unit tests for the lambda_handler method that is adding items to dynamodb table

Short animation of the /test agent generating a test file

Using Amazon Q Developer /test agent to generate unit tests

/test invoked within the IDE

Using Amazon Q Developer Generate Tests within IDE from code selection to develop unit tests

Note: The Q Developer agent for unit tests supports Java and Python projects in VS Code and JetBrains IDEs. see Language and framework support for unit test generation with /test. The /test feature handles various special cases, such as unsupported languages or frameworks, non-public methods in Java, and reaching monthly usage limits. It’s designed to provide a smooth user experience with helpful guidance throughout the process.

Enhancing Code Quality and Security (/review)

Code reviews have become an indispensable part of maintaining high standards in software development, and Amazon Q Developer’s new /review feature is transforming this critical process with powerful AI-driven code analysis. This innovative tool brings comprehensive code analysis capabilities right to your fingertips, enabling development teams to identify and address potential issues before they evolve into serious problems. Users can benefit from continuous code scanning that works seamlessly as they write, while receiving detailed issue reports complete with clear explanations and actionable recommendations. The feature even goes a step further by offering in-place code fixes, making it easier than ever to implement necessary improvements directly within your code.

The /review feature’s security detection capabilities cover a range of potential issues, ensuring thorough code analysis across multiple dimensions. Q Developer /review feature performs static application security testing (SAST) to identify security vulnerabilities, implements secrets detection to prevent the exposure of sensitive information, and analyzes infrastructure as code (IaC) files for potential issues. This essentially shifting security further left in the SDLC enabling developers to detect security vulnerabilities early in the development cycle before code gets committed to the repository thus improving overall security posture and code quality. Additionally, the tool evaluates code quality factors that might affect maintainability and efficiency, assesses potential deployment risks, and conducts software composition analysis (SCA) for third-party code. This comprehensive approach to code review helps development teams maintain high-quality, secure, and efficient codebases while significantly streamlining the review process.

In the below example, you can see how you can leverage /review feature to perform code scanning across the entire application workspace that includes both application python code and infrastructure terraform code and subsequently remediate it. Optionally, you can also choose to scan active opened files in the IDE.

Prompt:

/review

Short animation of the /review agent generating prioritized list of issues

Note: The /review feature maintains quotas to ensure optimal performance, with limits on input artifact size and source code size for both auto reviews and full project scans. More details can be found here

Conclusion

The innovative agents in Amazon Q Developer – /doc, /test, and /review – directly address some of the most challenging and time-intensive aspects of the development lifecycle, from documentation management to testing and code review. By automating crucial tasks like README creation or maintenance, unit test generation, and comprehensive code analysis, development teams can significantly enhance their productivity while maintaining high standards of code quality and security. The ability to catch potential issues early and streamline development lifecycle empowers teams to work more efficiently and effectively than ever before. However, it’s crucial to remember that these AI-powered features are designed to complement rather than replace human expertise – they serve as intelligent assistants that augment developers’ capabilities while still relying on their professional judgment to ensure optimal project outcomes. These tools stand as prime examples of how AI can be leveraged to overcome traditional development challenges while enabling teams to focus on what matters most: creating exceptional software. Embrace these new features, and take your development process to the next level with Amazon Q Developer. To learn more about Amazon Q Developer and explore innovative ways of accelerating software development refer to the Q Developer documentation. These agents are part of Q Developer’s expansive free tier of features, you can get started with them today!

Ryan Yanchuleff

Ryan is a Senior Specialist Solutions Architect for the Worldwide Specialist Organization focused on all things Generative AI. He has a passion for helping startups build new solutions to realize their ideas and has built more than a few startups himself. When he’s not playing with technology, he enjoys spending time with his wife and two kids and working on his next home renovation project.

Janardhan Molumuri

Janardhan Molumuri is a Principal Technical Leader at AWS. He has over two decades of Engineering leadership experience advising customers on Cloud Adoption strategies and emerging technologies including generative AI. He has passion for speaking, writing, and enjoys exploring technology trends to solve problems at scale.

Migrate from Standard brokers to Express brokers in Amazon MSK using Amazon MSK Replicator

Post Syndicated from Subham Rakshit original https://aws.amazon.com/blogs/big-data/migrate-from-standard-brokers-to-express-brokers-in-amazon-msk-using-amazon-msk-replicator/

Amazon Managed Streaming for Apache Kafka (Amazon MSK) now offers a new broker type called Express brokers. It’s designed to deliver up to 3 times more throughput per broker, scale up to 20 times faster, and reduce recovery time by 90% compared to Standard brokers running Apache Kafka. Express brokers come preconfigured with Kafka best practices by default, support Kafka APIs, and provide the same low latency performance that Amazon MSK customers expect, so you can continue using existing client applications without any changes. Express brokers provide straightforward operations with hands-free storage management by offering unlimited storage without pre-provisioning, eliminating disk-related bottlenecks. To learn more about Express brokers, refer to Introducing Express brokers for Amazon MSK to deliver high throughput and faster scaling for your Kafka clusters.

Creating a new cluster with Express brokers is straightforward, as described in Amazon MSK Express brokers. However, if you have an existing MSK cluster, you need to migrate to a new Express based cluster. In this post, we discuss how you should plan and perform the migration to Express brokers for your existing MSK workloads on Standard brokers. Express brokers offer a different user experience and a different shared responsibility boundary, so using them on an existing cluster is not possible. However, you can use Amazon MSK Replicator to copy all data and metadata from your existing MSK cluster to a new cluster comprising of Express brokers.

MSK Replicator offers a built-in replication capability to seamlessly replicate data from one cluster to another. It automatically scales the underlying resources, so you can replicate data on demand without having to monitor or scale capacity. MSK Replicator also replicates Kafka metadata, including topic configurations, access control lists (ACLs), and consumer group offsets.

In the following sections, we discuss how to use MSK Replicator to replicate the data from a Standard broker MSK cluster to an Express broker MSK cluster and the steps involved in migrating the client applications from the old cluster to the new cluster.

Planning your migration

Migrating from Standard brokers to Express brokers requires thorough planning and careful consideration of various factors. In this section, we discuss key aspects to address during the planning phase.

Assessing the source cluster’s infrastructure and needs

It’s crucial to evaluate the capacity and health of the current (source) cluster to make sure it can handle additional consumption during migration, because MSK Replicator will retrieve data from the source cluster. Key checks include:

    • CPU utilization – The combined CPU User and CPU System utilization per broker should remain below 60%.
    • Network throughput – The cluster-to-cluster replication process adds extra egress traffic, because it might need to replicate the existing data based on business requirements along with the incoming data. For instance, if the ingress volume is X GB/day and data is retained in the cluster for 2 days, replicating the data from the earliest offset would cause the total egress volume for replication to be 2X GB. The cluster must accommodate this increased egress volume.

Let’s take an example where in your existing source cluster you have an average data ingress of 100 MBps and peak data ingress of 400 MBps with retention of 48 hours. Let’s assume you have one consumer of the data you produce to your Kafka cluster, which means that your egress traffic will be same compared to your ingress traffic. Based on this requirement, you can use the Amazon MSK sizing guide to calculate the broker capacity you need to safely handle this workload. In the spreadsheet, you will need to provide your average and maximum ingress/egress traffic in the cells, as shown in the following screenshot.

Because you need to replicate all the data produced in your Kafka cluster, the consumption will be higher than the regular workload. Taking this into account, your overall egress traffic will be at least twice the size of your ingress traffic.
However, when you run a replication tool, the resulting egress traffic will be higher than twice the ingress because you also need to replicate the existing data along with the new incoming data in the cluster. In the preceding example, you have an average ingress of 100 MBps and you retain data for 48 hours, which means that you have a total of approximately 18 TB of existing data in your source cluster that needs to be copied over on top of the new data that’s coming through. Let’s further assume that your goal for the replicator is to catch up in 30 hours. In this case, your replicator needs to copy data at 260 MBps (100 MBps for ingress traffic + 160 MBps (18 TB/30 hours) for existing data) to catch up in 30 hours. The following figure illustrates this process.

Therefore, in the sizing guide’s egress cells, you need to add an additional 260 MBps to your average data out and peak data out to estimate the size of the cluster you should provision to complete the replication safely and on time.

Replication tools act as a consumer to the source cluster, so there is a chance that this replication consumer can consume higher bandwidth, which can negatively impact the existing application client’s produce and consume requests. To control the replication consumer throughput, you can use a consumer-side Kafka quota in the source cluster to limit the replicator throughput. This makes sure that the replicator consumer will throttle when it goes beyond the limit, thereby safeguarding the other consumers. However, if the quota is set too low, the replication throughput will suffer and the replication might never end. Based on the preceding example, you can set a quota for the replicator to be at least 260 MBps, otherwise the replication will not finish in 30 hours.

  • Volume throughput – Data replication might involve reading from the earliest offset (based on business requirement), impacting your primary storage volume, which in this case is Amazon Elastic Block Store (Amazon EBS). The VolumeReadBytes and VolumeWriteBytes metrics should be checked to make sure the source cluster volume throughput has additional bandwidth to handle any additional read from the disk. Depending on the cluster size and replication data volume, you should provision storage throughput in the cluster. With provisioned storage throughput, you can increase the Amazon EBS throughput up to 1000 MBps depending on the broker size. The maximum volume throughput can be specified depending on broker size and type, as mentioned in Manage storage throughput for Standard brokers in a Amazon MSK cluster. Based on the preceding example, the replicator will start reading from the disk and the volume throughput of 260 MBps will be shared across all the brokers. However, existing consumers can lag, which will cause reading from the disk, thereby increasing the storage read throughput. Also, there is storage write throughput due to incoming data from the producer. In this scenario, enabling provisioned storage throughput will increase the overall EBS volume throughput (read + write) so that existing producer and consumer performance doesn’t get impacted due to the replicator reading data from EBS volumes.
  • Balanced partitions – Make sure partitions are well-distributed across brokers, with no skewed leader partitions.

Depending on the assessment, you might need to vertically scale up or horizontally scale out the source cluster before migration.

Assessing the target cluster’s infrastructure and needs

Use the same sizing tool to estimate the size of your Express broker cluster. Typically, fewer Express brokers might be needed compared to Standard brokers for the same workload because depending on the instance size, Express brokers allow up to three times more ingress throughput.

Configuring Express Brokers

Express brokers employ opinionated and optimized Kafka configurations, so it’s important to differentiate between configurations that are read-only and those that are read/write during planning. Read/write broker-level configurations should be configured separately as a pre-migration step in the target cluster. Although MSK Replicator will replicate most topic-level configurations, certain topic-level configurations are always set to default values in an Express cluster: replication-factor, min.insync.replicas, and unclean.leader.election.enable. If the default values differ from the source cluster, these configurations will be overridden.

As part of the metadata, MSK Replicator also copies certain ACL types, as mentioned in Metadata replication. It doesn’t explicitly copy the write ACLs except the deny ones. Therefore, if you’re using SASL/SCRAM or mTLS authentication with ACLs rather than AWS Identity and Access Management (IAM) authentication, write ACLs need to be explicitly created in the target cluster.

Client connectivity to the target cluster

Deployment of the target cluster can occur within the same virtual private cloud (VPC) or a different one. Consider any changes to client connectivity, including updates to security groups and IAM policies, during the planning phase.

Migration strategy: All at once vs. wave

Two migration strategies can be adopted:

  • All at once – All topics are replicated to the target cluster simultaneously, and all clients are migrated at once. Although this approach simplifies the process, it generates significant egress traffic and involves risks to multiple clients if issues arise. However, if there is any failure, you can roll back by redirecting the clients to use the source cluster. It’s recommended to perform the cutover during non-business hours and communicate with stakeholders beforehand.
  • Wave – Migration is broken into phases, moving a subset of clients (based on business requirements) in each wave. After each phase, the target cluster’s performance can be evaluated before proceeding. This reduces risks and builds confidence in the migration but requires meticulous planning, especially for large clusters with many microservices.

Each strategy has its pros and cons. Choose the one that aligns best with your business needs. For insights, refer to Goldman Sachs’ migration strategy to move from on-premises Kafka to Amazon MSK.

Cutover plan

Although MSK Replicator facilitates seamless data replication with minimal downtime, it’s essential to devise a clear cutover plan. This includes coordinating with stakeholders, stopping producers and consumers in the source cluster, and restarting them in the target cluster. If a failure occurs, you can roll back by redirecting the clients to use the source cluster.

Schema registry

When migrating from a Standard broker to an Express broker cluster, schema registry considerations remain unaffected. Clients can continue using existing schemas for both producing and consuming data with Amazon MSK.

Solution overview

In this setup, two Amazon MSK provisioned clusters are deployed: one with Standard brokers (source) and the other with Express brokers (target). Both clusters are located in the same AWS Region and VPC, with IAM authentication enabled. MSK Replicator is used to replicate topics, data, and configurations from the source cluster to the target cluster. The replicator is configured to maintain identical topic names across both clusters, providing seamless replication without requiring client-side changes.

During the first phase, the source MSK cluster handles client requests. Producers write to the clickstream topic in the source cluster, and a consumer group with the group ID clickstream-consumer reads from the same topic. The following diagram illustrates this architecture.

When data replication to the target MSK cluster is complete, we need to evaluate the health of the target cluster. After confirming the cluster is healthy, we need to migrate the clients in a controlled manner. First, we need to stop the producers, reconfigure them to write to the target cluster, and then restart them. Then, we need to stop the consumers after they have processed all remaining records in the source cluster, reconfigure them to read from the target cluster, and restart them. The following diagram illustrates the new architecture.

After verifying that all clients are functioning correctly with the target cluster using Express brokers, we can safely decommission the source MSK cluster with Standard brokers and the MSK Replicator.

Deployment Steps

In this section, we discuss the step-by-step process to replicate data from an MSK Standard broker cluster to an Express broker cluster using MSK Replicator and also the client migration strategy. For the purpose of the blog, “all at once” migration strategy is used.

Provision the MSK cluster

Download the AWS CloudFormation template to provision the MSK cluster. Deploy the following in us-east-1 with stack name as migration.

This will create the VPC, subnets, and two Amazon MSK provisioned clusters: one with Standard brokers (source) and another with Express brokers (target) within the VPC configured with IAM authentication. It will also create a Kafka client Amazon Elastic Compute Cloud (Amazon EC2) instance where from we can use the Kafka command line to create and view Kafka topics and produce and consume messages to and from the topic.

Configure the MSK client

On the Amazon EC2 console, connect to the EC2 instance named migration-KafkaClientInstance1 using Session Manager, a capability of AWS Systems Manager.

After you log in, you need to configure the source MSK cluster bootstrap address to create a topic and publish data to the cluster. You can get the bootstrap address for IAM authentication from the details page for the MSK cluster (migration-standard-broker-src-cluster) on the Amazon MSK console, under View Client Information. You also need to update the producer.properties and consumer.properties files to reflect the bootstrap address of the standard broker cluster.

sudo su - ec2-user

export BS_SRC=<<SOURCE_MSK_BOOTSTRAP_ADDRESS>>
sed -i "s/BOOTSTRAP_SERVERS_CONFIG=/BOOTSTRAP_SERVERS_CONFIG=${BS_SRC}/g" producer.properties 
sed -i "s/bootstrap.servers=/bootstrap.servers=${BS_SRC}/g" consumer.properties

Create a topic

Create a clickstream topic using the following commands:

/home/ec2-user/kafka/bin/kafka-topics.sh --bootstrap-server=$BS_SRC \
--create --replication-factor 3 --partitions 3 \
--topic clickstream \
--command-config=/home/ec2-user/kafka/config/client_iam.properties

Produce and consume messages to and from the topic

Run the clickstream producer to generate events in the clickstream topic:

cd /home/ec2-user/clickstream-producer-for-apache-kafka/

java -jar target/KafkaClickstreamClient-1.0-SNAPSHOT.jar -t clickstream \
-pfp /home/ec2-user/producer.properties -nt 8 -rf 3600 -iam \
-gsr -gsrr <<REGION>> -grn default-registry -gar

Open another Session Manager instance and from that shell, run the clickstream consumer to consume from the topic:

cd /home/ec2-user/clickstream-consumer-for-apache-kafka/

java -jar target/KafkaClickstreamConsumer-1.0-SNAPSHOT.jar -t clickstream \
-pfp /home/ec2-user/consumer.properties -nt 3 -rf 3600 -iam \
-gsr -gsrr <<REGION>> -grn default-registry

Keep the producer and consumer running. If not interrupted, the producer and consumer will run for 60 minutes before it exits. The -rf parameter controls how long the producer and consumer will run.

Create an MSK replicator

To create an MSK replicator, complete the following steps:

  1. On the Amazon MSK console, choose Replicators in the navigation pane.
  2. Choose Create replicator.
  3. In the Replicator details section, enter a name and optional description.

  1. In the Source cluster section, provide the following information:
    1. For Cluster region, choose us-east-1.
    2. For MSK cluster, enter the MSK cluster Amazon Resource Name (ARN) for the Standard broker.

After the source cluster is selected, it automatically selects the subnets associated with the primary cluster and the security group associated with the source cluster. You can also select additional security groups.

Make sure that the security groups have outbound rules to allow traffic to your cluster’s security groups. Also make sure that your cluster’s security groups have inbound rules that accept traffic from the replicator security groups provided here.

  1. In the Target cluster section, for MSK cluster¸ enter the MSK cluster ARN for the Express broker.

After the target cluster is selected, it automatically selects the subnets associated with the primary cluster and the security group associated with the source cluster. You can also select additional security groups.

Now let’s provide the replicator settings.

  1. In the Replicator settings section, provide the following information:
    1. For the purpose of the example, we have kept the topics to replicate as a default value that would replicate all topics from primary to secondary cluster.
    2. For Replicator starting position, we configure it to replicate from the earliest offset, so that we can get all the events from the start of the source topics.
    3. To configure the topic name in the secondary cluster as identical to the primary cluster, we select Keep the same topic names for Copy settings. This makes sure that the MSK clients don’t need to add a prefix to the topic names.

    1. For this example, we keep the Consumer Group Replication setting as default (make sure it’s enabled to allow redirected clients resume processing data from the last processed offset).
    2. We set Target Compression type as None.

The Amazon MSK console will automatically create the required IAM policies. If you’re deploying using the AWS Command Line Interface (AWS CLI), SDK, or AWS CloudFormation, you have to create the IAM policy and use it as per your deployment process.

  1. Choose Create to create the replicator.

The process will take around 15–20 minutes to deploy the replicator. When the MSK replicator is running, this will be reflected in the status.

Monitor replication

When the MSK replicator is up and running, monitor the MessageLag metric. This metric indicates how many messages are yet to be replicated from the source MSK cluster to the target MSK cluster. The MessageLag metric should come down to 0.

Migrate clients from source to target cluster

When the MessageLag metric reaches 0, it indicates that all messages have been replicated from the source MSK cluster to the target MSK cluster. At this stage, you can cut over client applications from the source to the target cluster. Before initiating this step, confirm the health of the target cluster by reviewing the Amazon MSK metrics in Amazon CloudWatch and making sure that the client applications are functioning properly. Then complete the following steps:

  1. Stop the producers writing data to the source (old) cluster with Standard brokers and reconfigure them to write to the target (new) cluster with Express brokers.
  2. Before migrating the consumers, make sure that the MaxOffsetLag metric for the consumers has dropped to 0, confirming that they have processed all existing data in the source cluster.
  3. When this condition is met, stop the consumers and reconfigure them to read from the target cluster.

The offset lag happens if the consumer is consuming slower than the rate the producer is producing data. The flat line in the following metric visualization shows that the producer has stopped producing to the source cluster while the consumer attached to it continues to consume the existing data and eventually consumes all the data, therefore the metric goes to 0.

  1. Now you can update the bootstrap address in properties and consumer.properties to point to the target Express based MSK cluster. You can get the bootstrap address for IAM authentication from the MSK cluster (migration-express-broker-dest-cluster) on the Amazon MSK console under View Client Information.
export BS_TGT=<<TARGET_MSK_BOOTSTRAP_ADDRESS>>
sed -i "s/BOOTSTRAP_SERVERS_CONFIG=.*/BOOTSTRAP_SERVERS_CONFIG=${BS_TGT}/g" producer.properties
sed -i "s/bootstrap.servers=.*/bootstrap.servers=${BS_TGT}/g" consumer.properties

  1. Run the clickstream producer to generate events in the clickstream topic:
cd /home/ec2-user/clickstream-producer-for-apache-kafka/

java -jar target/KafkaClickstreamClient-1.0-SNAPSHOT.jar -t clickstream \
-pfp /home/ec2-user/producer.properties -nt 8 -rf 60 -iam \
-gsr -gsrr <<REGION>> -grn default-registry -gar

  1. In another Session Manager instance and from that shell, run the clickstream consumer to consume from the topic:
cd /home/ec2-user/clickstream-consumer-for-apache-kafka/

java -jar target/KafkaClickstreamConsumer-1.0-SNAPSHOT.jar -t clickstream \
-pfp /home/ec2-user/consumer.properties -nt 3 -rf 60 -iam \
-gsr -gsrr <<REGION>> -grn default-registry

We can see that the producers and consumers are now producing and consuming to the target Express based MSK cluster. The producers and consumers will run for 60 seconds before they exit.

The following screenshot shows producer-produced messages to the new Express based MSK cluster for 60 seconds.

Migrate stateful applications

Stateful applications such as Kafka Streams, KSQL, Apache Spark, and Apache Flink use their own checkpointing mechanisms to store consumer offsets instead of relying on Kafka’s consumer group offset mechanism. When migrating topics from a source cluster to a target cluster, the Kafka offsets in the source will differ from those in the target. As a result, migrating a stateful application along with its state requires careful consideration, because the existing offsets are incompatible with the target cluster’s offsets. Before migrating stateful applications, it is crucial to stop producers and make sure that consumer applications have processed all data from the source MSK cluster.

Migrate Kafka Streams and KSQL applications

Kafka Streams and KSQL store consumer offsets in internal changelog topics. It is advisable not to replicate these internal changelog topics to the target MSK cluster. Instead, the Kafka Streams application should be configured to start from the earliest offset of the source topics in the target cluster. This allows the state to be rebuilt. However, this method results in duplicate processing, because all the data in the topic is reprocessed. Therefore, the target destination (such as a database) must be idempotent to handle these duplicates effectively.

Express brokers don’t allow configuring segment.bytes to optimize performance. Therefore, the internal topics need to be manually created before the Kafka Streams application is migrated to the new Express based cluster. For more information, refer to Using Kafka Streams with MSK Express brokers and MSK Serverless.

Migrate Spark applications

Spark stores offsets in its checkpoint location, which should be a file system compatible with HDFS, such as Amazon Simple Storage Service (Amazon S3). After migrating the Spark application to the target MSK cluster, you should remove the checkpoint location, causing the Spark application to lose its state. To rebuild the state, configure the Spark application to start processing from the earliest offset of the source topics in the target cluster. This will lead to re-processing all the data from the start of the topic and therefore will generate duplicate data. Consequently, the target destination (such as a database) must be idempotent to effectively handle these duplicates.

Migrate Flink applications

Flink stores consumer offsets within the state of its Kafka source operator. When checkpoints are completed, the Kafka source commits the current consuming offset to provide consistency between Flink’s checkpoint state and the offsets committed on Kafka brokers. Unlike other systems, Flink applications don’t rely on the __consumer_offsets topic to track offsets; instead, they use the offsets stored in Flink’s state.

During Flink application migration, one approach is to start the application without a Savepoint. This approach discards the entire state and reverts to reading from the last committed offset of the consumer group. However, this prevents the application from accurately rebuilding the state of downstream Flink operators, leading to discrepancies in computation results. To address this, you can either avoid replicating the consumer group of the Flink application or assign a new consumer group to the application when restarting it in the target cluster. Additionally, configure the application to start reading from the earliest offset of the source topics. This enables re-processing all data from the source topics and rebuilding the state. However, this method will result in duplicate data, so the target system (such as a database) must be idempotent to handle these duplicates effectively.

Alternatively, you can reset the state of the Kafka source operator. Flink uses operator IDs (UIDs) to map the state to specific operators. When restarting the application from a Savepoint, Flink matches the state to operators based on their assigned IDs. It is recommended to assign a unique ID to each operator to enable seamless state restoration from Savepoints. To reset the state of the Kafka source operator, change its operator ID. Passing the operator ID as a parameter in a configuration file can simplify this process. Restart the Flink application with parameter --allowNonRestoredState (if you are running self-managed Flink). This will reset only the state of the Kafka source operator, leaving other operator states unaffected. As a result, the Kafka source operator resumes from the last committed offset of the consumer group, avoiding full reprocessing and state rebuilding. Although this might still produce some duplicates in the output, it results in no data loss. This approach is applicable only when using the DataStream API to build Flink applications.

Conclusion

Migrating from a Standard broker MSK cluster to an Express broker MSK cluster using MSK Replicator provides a seamless, efficient transition with minimal downtime. By following the steps and strategies discussed in this post, you can take advantage of the high-performance, cost-effective benefits of Express brokers while maintaining data consistency and application uptime.

Ready to optimize your Kafka infrastructure? Start planning your migration to Amazon MSK Express brokers today and experience improved scalability, speed, and reliability. For more details, refer to the Amazon MSK Developer Guide.


About the Author

Subham Rakshit is a Senior Streaming Solutions Architect for Analytics at AWS based in the UK. He works with customers to design and build streaming architectures so they can get value from analyzing their streaming data. His two little daughters keep him occupied most of the time outside work, and he loves solving jigsaw puzzles with them. Connect with him on LinkedIn.