Tag Archives: Intermediate (200)

Automate sender ID registration in AWS End User Messaging

Post Syndicated from Sarath Kumar Kallayil Sreedharan original https://aws.amazon.com/blogs/messaging-and-targeting/automate-sender-id-registration-in-aws-end-user-messaging/

AWS End User Messaging makes it possible to send SMS, MMS, push notifications, WhatsApp messages, and text to voice globally. When you send SMS, MMS, and voice messages with AWS End User Messaging, you must use a specific origination identity that supports sending these messages. Messaging options vary by country and include toll-free numbers (TFN), 10-digit long codes (US 10DLC), long codes, short codes, and sender IDs. To check a country’s available options, refer to Supported countries and regions for SMS messaging with AWS End User Messaging SMS.

This post explains how to programmatically register sender IDs, which can be used in many countries around the globe. The registration process makes it possible for businesses and organizations to send messages using an alphanumeric identifier instead of a phone number, making communications more professional and recognizable to recipients. For example, a fictitious company Example Corp could use the sender ID EXAMPLECO to send SMS. To learn more about sender ID registration, refer to Sender IDs in AWS End User Messaging SMS.

This post explores the AWS End User Messaging APIs required for programmatically registering sender IDs for the Indonesia and India. These sample scripts serve as a reference for sender ID registration in other countries. This automation approach simplifies the registration process, saving time and effort for businesses using AWS End User Messaging for their communication needs.

AWS End User Messaging APIs for sender ID registration

The AWS End User Messaging V2 API contains a set of actions that focus on sender ID registration management:

  • DescribeRegistrationTypeDefinitions – Retrieves registration type details for different countries. You can use DescribeRegistrationFieldDefinitions to view the requirements for creating, filling out, and submitting each registration type.
  • CreateRegistration – Creates a new registration. The RegistrationType field controls whether this is a registration for toll-free, 10DLC, or sender ID. This post will use a sender ID.
  • DescribeRegistrationFieldDefinitions – Retrieves field requirements for a specific registration type (retrieved by DescribeRegistrationTypeDefinitions).
  • PutRegistrationFieldValue – This action must be repeated for all required fields (retrieved by DescribeRegistrationFieldDefinitions).
  • CreateRegistrationAttachment – Uploads a required attachment (for example, a letter of authorization) for registration based on country-specific requirements.
  • SubmitRegistrationVersion – Submits the specified registration for review and approval. Make sure to verify all data is accurate before submitting the registration. The review process consists of the following steps:
    • After your script submits the registration, the initial status appears as CREATED and typically changes to REVIEWING within 24 hours.
    • After submission, your sender ID registration can’t be modified or deleted until the third-party registrar completes their review process.
    • If the status remains CREATED for over 24 hours after you’ve submitted your registration, open a support case for assistance.

Available actions for sender ID registration

As you manage your messaging campaigns in AWS End User Messaging SMS, several APIs are available to help you handle sender ID registrations efficiently:

  • CreateRegistrationVersion – Creates a new version of the registration and increases the VersionNumber. The previous version of the registration becomes read-only. This is useful for updating registration information while maintaining historical records.
  • DescribeRegistrationAttachments – Retrieves the specified registration attachments or all registration attachments associated with your AWS account. This helps in managing and reviewing documents linked to your registrations.
  • DescribeRegistrationFieldValues – Retrieves the specified registration field values. You can use this API to review current registration details for a specific version.
  • DescribeRegistrations – Retrieves the specified registrations and provides an overview of all your sender ID registrations, which is useful for multi-campaign management.
  • DescribeRegistrationSectionDefinitions – Retrieves the specified registration section definitions. You can use DescribeRegistrationSectionDefinitions to view the requirements for creating, filling out, and submitting each registration type. This API helps you understand the structure and requirements of different registration sections.
  • DescribeRegistrationVersions – Retrieves the specified registration version. You can use this API to track changes and view historical versions of a registration.

The following are important considerations for registration:

  • Most registration submissions undergo review by an independent third-party organization. This is a standard industry practice across SMS providers.
  • AWS does not review your registrations. It is important to complete this registration process with the understanding that AWS merely facilitates the submission process. AWS does not participate in or influence the third-party review process.
  • Each country has its own review process and timeline. Each registration is examined on a first-in/first-out basis by the registrar for each country. The registration review is conducted by external personnel unfamiliar with your company or use case. Therefore, it is crucial to provide clear and concise responses in your application.
  • After submitting your registration, the status begins as CREATED and typically transitions to REVIEWING within 24 hours
  • If AWS is able to provide you with a sender ID, AWS sends you an estimated time frame required for its provisioning. In many countries, AWS can provide you with a sender ID within 2–4 weeks. However, in some countries, it can take several weeks to obtain a sender ID.

AWS End User Messaging API usage flow for sender ID registration

The API flow consists of the following steps:

  1. Call DescribeRegistrationTypeDefinitions to understand available registration types.
  2. Use CreateRegistration to initiate the registration process.
  3. To obtain details about the required fields, call DescribeRegistrationFieldDefinitions.
  4. Use PutRegistrationFieldValue multiple times to populate all required fields.
  5. If needed, use CreateRegistrationAttachment to upload supporting documents.
  6. Finally, call SubmitRegistrationVersion to submit the registration for review.
  7. Use DescribeRegistrations periodically to check the status of the registration.

This API flow enables a fully automated sender ID registration process for supported countries. Businesses can efficiently manage registrations across various regulatory environments and geographical locations.

Registration field format

The AWS End User Messaging API uses a specific format to define the registration fields:

  • SectionPath – Represents the hierarchical location of a field within the registration form’s structure. For example, "SectionPath": "companyInfo".
  • FieldPath – The complete path to a specific field, combining the SectionPath with the field name. For example, "FieldPath": "companyInfo.companyName".
  • FieldType – Specifies the data type of the field (such as TEXT, SELECT, or ATTACHMENT). For example, "FieldType": "TEXT".
  • FieldRequirement – Indicates whether the field is REQUIRED, OPTIONAL, or CONDITIONAL. For example, "FieldRequirement": "REQUIRED".

Understanding these attributes is crucial for effective API interaction during the registration process. They define both the structure of your API calls and the necessary data inputs.

The following code is the subset of the response of DescribeRegistrationFieldDefinitions for the United Kingdom registration type (RegistrationType):

{
            "SectionPath": "companyInfo",
            "FieldPath": "companyInfo.companyName",
            "FieldType": "TEXT",
            "FieldRequirement": "REQUIRED",
            "TextValidation": {
                "MinLength": 1,
                "MaxLength": 100,
                "Pattern": "^(?=\\s*\\S)[\\s\\S]+$"
            },
            "DisplayHints": {
                "Title": "Company name",
                "ShortDescription": "Legal name which your company is registered under.",
                "ExampleTextValue": "Example Corp"
            }
        }
        
     {
            "SectionPath": "senderIdInfo",
"FieldPath": "senderIdInfo.senderIdDescription",
            "FieldType": "TEXT",
            "FieldRequirement": "OPTIONAL",
            "TextValidation": {
                "MinLength": 1,
                "MaxLength": 500,
                "Pattern": "^(?=\\s*\\S)[\\s\\S]+$"
            },
            "DisplayHints": {
                "Title": "Sender ID description",
                "ShortDescription": "If it is not obvious, explain the connection between your company name and this sender ID."
            }
        }
        
        {
            "SectionPath": "senderIdInfo",
            "FieldPath": "senderIdInfo.letterOfAuthorization",
            "FieldType": "ATTACHMENT",
            "FieldRequirement": "CONDITIONAL",
            "DisplayHints": {
                "Title": "Letter of authorization image",
                "ShortDescription": "Image of your signed letter of authorization (LOA)"
            }
        }
        {
            "SectionPath": "messagingUseCase",
            "FieldPath": "messagingUseCase.monthlyMessageVolume",
            "FieldType": "SELECT",
            "FieldRequirement": "REQUIRED",
            "SelectValidation": {
                "MinChoices": 1,
                "MaxChoices": 1,
                "Options": [
                    "10",
                    "100",
                    "1,000",
                    "10,000",
                    "100,000",
                    "250,000",
                    "500,000",
                    "750,000",
                    "1,000,000",
                    "5,000,000",
                    "10,000,000+"
                ]
            },
            "DisplayHints": {
                "Title": "Monthly SMS volume",
                "ShortDescription": "Estimated number of SMS messages which will be sent from this sender ID each month."
            }
        }

Prerequisites

Before running either script, you must have the following:

Automate sender ID registration for Indonesia

The Indonesia registration process involves several additional requirements that vary based on your company’s location and business type. All companies must submit XL Axiata’s Letter of Authorization (LOA). Indonesian companies need additional LOAs from Telkomsel, IOH, and Smartfren, plus NIB and NPWP documents. Apply IDR9K and the company stamp to each LOA. For sample documents, refer to Indonesia sender ID registration in AWS End User Messaging SMS. Businesses operating in the money lending sector are required to provide an operating license issued by the Financial Services Authority (Otoritas Jasa Keuangan—OJK).

In this section, we break down the Python script for Indonesia registration.

Before running the registration script, you must first set the necessary variables, with your company actual data. The following is a sample file with the variables required for Indonesia local sender ID registration. Provide the correct path for LOA files (telkomsel_loa.png,ioh_loa.png, xl_axiata_loa.png, smartfren_loa.png,regulatory_licence.png, proof_of_sender_id.png, nomor_pokokWajib_pajak_document.png, and nomor_induk_berusaha_document.png).

Save the following file as indonesia_config.py:

# =============================================================================
# INDONESIA SENDER ID REGISTRATION CONFIGURATION
# =============================================================================
#AWS Region Details
# ---------------------
REGION_NAME='us-west-2'
# Registration Settings
# ---------------------
REGISTRATION_TYPE = 'ID_SENDER_ID_REGISTRATION'  # Registration type for Indonesia
REGISTRATION_NAME = 'INDONESIA_TEST_SENDER_ID'    # Name tag for this registration
# Sender ID Information
# --------------------
# The sender ID to register. Must be between 3 and 11 alphanumeric characters.
# Must contain at least one letter. Example: 'EXAMPLE'
SENDER_ID = 'DEMO'
# Company Information
# ------------------
# Legal name of your company
COMPANY_NAME = 'Example Corp'
# Legal identification number of your company (such as EIN or VAT)
# Must be alphanumeric, 1-30 characters
COMPANY_ID = '123456789'
# Full URL of your company's website
COMPANY_WEBSITE = 'https://www.example.com'
# Select the vertical which most closely aligns with your company's area of business
# Options: Agriculture, Communication, Construction, Education, Energy, Entertainment,
# Financial, Government, Healthcare, Hospitality, Insurance, Manufacturing,
# Real estate, Retail, Technology, Other
AREA_OF_BUSINESS = ['Other']
# Company Address
# ---------------
# Physical street address associated with your company
COMPANY_ADDRESS = '123 Main Street'
# City where the physical address is located
COMPANY_CITY = 'Jakarta'
# Two-digit ISO country code where the physical address is located
COUNTRY_CODE = 'ID'
# Contact Information
# ------------------
# Email address of your company's point of contact
CONTACT_EMAIL = '[email protected]'
# Phone number of your company's point of contact
CONTACT_PHONE = '+6281234567890'
# Messaging Use Case
# -----------------
# Description of your use case for sending SMS messages with this sender ID
USE_CASE_DESCRIPTION = 'For One Time Messages'
# Select the category which most closely aligns with your use case
# Options: One-time passcodes, Account or security alerts, Purchase or delivery notifications,
# Public service announcements, Polling and surveys, Info on demand, Promotions and marketing, Other
USE_CASE_CATEGORY = ['One-time passcodes']
# Estimated number of SMS messages which will be sent from this sender ID each month
# Options: 10, 100, 1,000, 10,000, 100,000, 1,000,000, 10,000,000+
MONTHLY_MESSAGE_VOLUME = ['10,000']
# At least one sample is required of an SMS message which will be sent from this sender ID
# Maximum 306 characters
MESSAGE_SAMPLE = 'Your OTP is XXX'
# Document Paths
# --------------
# Update these paths to point to your actual document files
DOCUMENT_PATHS = {
    # Letter of authorization for Telkomsel (CONDITIONAL - required if company is local to Indonesia)
    # Download, complete, and attach the LOA from AWS documentation
    'TELKOMSEL_LOA': 'telkomsel_loa.png',
    
    # Letter of authorization for IOH (CONDITIONAL - required if company is local to Indonesia)
    # Download, complete, and attach the LOA from AWS documentation
    'IOH_LOA': 'ioh_loa.png',
    
    # Letter of authorization for XL Axiata (REQUIRED for all companies)
    # Download, complete, and attach the LOA from AWS documentation
    'XL_AXIATA_LOA': 'xl_axiata.png',
    
    # Letter of authorization for Smartfren (CONDITIONAL - required if company is local to Indonesia)
    # Download, complete, and attach the LOA from AWS documentation
    'SMARTFREN_LOA': 'smartfren_loa.png',
    
    # Regulatory agency license (OPTIONAL - required only if company's area of business is money lending)
    # Provide operating license from OJK (Otoritas Jasa Keuangan)
    'REGULATORY_LICENSE': 'regulatory_license.png',

Save the following file as indonesia_senderid_registration.py:

import boto3
from typing import Dict, Union, List
import logging
import importlib.util
import argparse
import time
# Set up logging
logging.basicConfig(level=logging.INFO, format='%(asctime)s - %(levelname)s - %(message)s')
logger = logging.getLogger(__name__)
def load_config(config_file):
    """Load configuration from a Python file"""
    spec = importlib.util.spec_from_file_location("config", config_file)
    config = importlib.util.module_from_spec(spec)
    spec.loader.exec_module(config)
    return config
class EndUserMessagingRegistrationIndonesia:
    def __init__(self, config):
        self.client = boto3.client('pinpoint-sms-voice-v2',region_name=config.REGION_NAME)
        self.registration_id = None
        self.config = config
        self.max_retries = 5
        self.retry_delay = 2
    def create_registration(self) -> str:
        """Create a new Sender ID registration"""
        try:
            response = self.client.create_registration(RegistrationType=self.config.REGISTRATION_TYPE,
                                                       Tags=[{'Key': 'Name', 'Value': self.config.REGISTRATION_NAME}])
            self.registration_id = response['RegistrationId']
            logger.info(f"Registration created with ID: {self.registration_id}")
            return self.registration_id
        except Exception as e:
            logger.error(f"Failed to create registration: {str(e)}")
            raise


    def create_attachment(self, file_path: str) -> str:
        """Create and upload attachments"""
        try:
            with open(file_path, 'rb') as file:
                response = self.client.create_registration_attachment(
                    AttachmentBody=file.read()
                )
            attachment_id = response['RegistrationAttachmentId']
            logger.info(f"Created attachment with ID: {attachment_id}")
            return attachment_id
        except Exception as e:
            logger.error(f"Failed to create attachment: {str(e)}")
            raise
    def wait_for_attachment(self, attachment_id: str) -> bool:
        """Wait for attachment upload to complete"""
        for attempt in range(self.max_retries):
            try:
                response = self.client.describe_registration_attachments(
                    RegistrationAttachmentIds=[attachment_id]
                )
                status = response['RegistrationAttachments'][0]['AttachmentStatus']
                if status == 'UPLOAD_COMPLETE':
                    return True
                logger.info(f"Attachment status: {status}, waiting...")
                time.sleep(self.retry_delay)
            except Exception as e:
                logger.error(f"Error checking attachment status: {str(e)}")
                time.sleep(self.retry_delay)
        return False
def update_registration_fields(self, fields: Dict[str, Union[str, List[str], Dict[str, str]]]):
        """Update registration fields with provided values"""
        if not self.registration_id:
            raise ValueError("Registration ID not set. Create registration first.")
        for field_path, value in fields.items():
            try:
                if isinstance(value, dict) and 'attachmentId' in value:
                    self.client.put_registration_field_value(
                        RegistrationId=self.registration_id,
                        FieldPath=field_path,
                        RegistrationAttachmentId=value['attachmentId']
                    )
                elif isinstance(value, list):
                    self.client.put_registration_field_value(
                        RegistrationId=self.registration_id,
                        FieldPath=field_path,
                        SelectChoices=value
                    )
                else:
                    self.client.put_registration_field_value(
                        RegistrationId=self.registration_id,
                        FieldPath=field_path,
                        TextValue=value
                    )
                logger.info(f"Updated field: {field_path}")
            except Exception as e:
                logger.error(f"Failed to update field {field_path}: {str(e)}")
                raise
    def submit_registration(self):
        """Submit the registration for review"""
        if not self.registration_id:
            raise ValueError("Registration ID not set. Create registration first.")
        try:
            self.client.submit_registration_version(RegistrationId=self.registration_id)
            logger.info("Registration submitted successfully")
        except Exception as e:
            logger.error(f"Failed to submit registration: {str(e)}")
            raise
def main():
    parser = argparse.ArgumentParser(description='Indonesia SMS Registration Tool')
    parser.add_argument('--config', required=True, help='Path to config file')
    args = parser.parse_args()
  config = load_config(args.config)
    registration = EndUserMessagingRegistrationIndonesia(config)
    registration.create_registration()
    # Document mappings
    document_mapping = {
        'TELKOMSEL_LOA': 'idSidSpecificInfo.letterOfAuthorization1',
        'IOH_LOA': 'idSidSpecificInfo.letterOfAuthorization2',
        'XL_AXIATA_LOA': 'idSidSpecificInfo.letterOfAuthorization3',
        'SMARTFREN_LOA': 'idSidSpecificInfo.letterOfAuthorization4',
        'REGULATORY_LICENSE': 'idSidSpecificInfo.regulatoryAgencyLicense',
        'PROOF_OF_SENDER_ID': 'senderIdInfo.proofOfSenderIdConnection',
        'NOMOR_POKOK_WAJIB_PAJAK_Document': 'idSidSpecificInfo.nomorPokokWajibPajakDocument',
        'NOMOR_INDUK_BERUSAHA_DOCUMENT': 'idSidSpecificInfo.nomorIndukBerusahaDocument',
    }
    # Process documents
    document_fields = {}
    for doc_type, file_path in config.DOCUMENT_PATHS.items():
        try:
            attachment_id = registration.create_attachment(file_path)
            if registration.wait_for_attachment(attachment_id):
                if doc_type in document_mapping:
                    field_path = document_mapping[doc_type]
                    document_fields[field_path] = {'attachmentId': attachment_id}
                    logger.info(f"Successfully processed {doc_type}")
        except Exception as e:
            logger.error(f"Failed to process {doc_type}: {str(e)}")
            raise
    # Text fields
    text_fields = {
        'senderIdInfo.senderId': config.SENDER_ID,
        'companyInfo.companyId': config.COMPANY_ID,
        'companyInfo.companyName': config.COMPANY_NAME,
        'companyInfo.website': config.COMPANY_WEBSITE,
        'companyInfo.areaOfBusiness': config.AREA_OF_BUSINESS,
        'companyAddress.address1': config.COMPANY_ADDRESS,
        'companyAddress.city': config.COMPANY_CITY,
        'companyAddress.isoCountryCode': config.COUNTRY_CODE,
        'contactInfo.emailAddress': config.CONTACT_EMAIL,
        'contactInfo.phoneNumber': config.CONTACT_PHONE,
        'messagingUseCase.useCaseCategory': config.USE_CASE_CATEGORY,
        'messagingUseCase.useCaseDescription': config.USE_CASE_DESCRIPTION,
        'messagingUseCase.monthlyMessageVolume': config.MONTHLY_MESSAGE_VOLUME,
        'messagingUseCase.optInDescription': config.USE_CASE_DESCRIPTION,
        'messageSamples.messageSample1': config.MESSAGE_SAMPLE
    }
    # Combine all fields
    all_fields = {**text_fields, **document_fields}
    registration.update_registration_fields(all_fields)
    registration.submit_registration()
if __name__ == "__main__":
    main()

Run the script: python indonesia_senderid_registration.py --config indonesia_config.py

Automate sender ID registration for India

Starting April 30, 2025, AWS will offer India sender ID registration through two Regions: Asia Pacific (Mumbai) and Asia Pacific (Hyderabad).

The sender ID registration process for India differs slightly; it doesn’t require an LOA attachment and includes additional fields specific to the Indian regulatory environment.

Before running the registration script, you must first set the necessary variables with your company’s actual data. The following is a sample file with the variables required for India sender ID registration. Modify and save the file as india_config.py:

# =============================================================================
# INDIA SENDER ID REGISTRATION CONFIGURATION
# =============================================================================
#AWS Region Details
# ---------------------
REGION_NAME='ap-south-1'
# Registration Settings
# ---------------------
REGISTRATION_TYPE = 'IN_SENDER_ID_REGISTRATION'  # Registration type for India
REGISTRATION_NAME = 'INDIA_TEST_SENDERID'        # Name tag for this registration
# Sender ID Information
# --------------------
# The sender ID to register. India sender IDs must be 3-6 alphabetic characters.
# Must exactly match the sender ID registered with TRAI (Telecom Regulatory Authority of India)
SENDER_ID = 'DEMO'
# Principal Entity ID (PEID) - REQUIRED
# The PEID received after completing registration with TRAI
ENTITY_ID = '123'
# Chain IDs (India Specific) - ALL REQUIRED
# ----------------------------------------
# Provide approved chain IDs from your DLT platform after creating telemarketer chains
# Chain ID for ROUTE LEDGER TECHNOLOGIES PRIVATE LIMITED
CHAIN_ID_1 = '456'
# Chain ID for Karix Mobile Pvt Ltd  
CHAIN_ID_2 = '789'
# Chain ID for Sinch Cloud Communication Services India Private Limited
CHAIN_ID_3 = '910'
# Chain ID for Infobip India Private Limited
CHAIN_ID_5 = '912'
# Company Information
# ------------------
# Legal name of your company
COMPANY_NAME = 'Example Corp'
# Legal identification number of your company (such as EIN or VAT)
# Must be alphanumeric, 1-30 characters
COMPANY_ID = '123456789'
# Full URL of your company's website
COMPANY_WEBSITE = 'https://www.example.com'
# Select the vertical which most closely aligns with your company's area of business
# Options: Agriculture, Communication, Construction, Education, Energy, Entertainment,
# Financial, Government, Healthcare, Hospitality, Insurance, Manufacturing,
# Real estate, Retail, Technology, Other
AREA_OF_BUSINESS = ['Other']
# Company Address
# ---------------
# Physical street address associated with your company
COMPANY_ADDRESS = '123 Main Street'
# City where the physical address is located
COMPANY_CITY = 'Any Town'
# Two-digit ISO country code where the physical address is located
COUNTRY_CODE = 'IN'
# Contact Information
# ------------------
# Email address of your company's point of contact
CONTACT_EMAIL = '[email protected]'
# Phone number of your company's point of contact
CONTACT_PHONE = '+12605550100'
# Messaging Use Case
# -----------------
# Description of your use case for sending SMS messages with this sender ID
USE_CASE_DESCRIPTION = 'For One Time Messages'
# Select the category which most closely aligns with your use case
# Options: One-time passcodes, Account or security alerts, Purchase or delivery notifications,
# Public service announcements, Polling and surveys, Info on demand, Other
# Note: India does not support 'Promotions and marketing' category
USE_CASE_CATEGORY = ['One-time passcodes']
# Estimated number of SMS messages which will be sent from this sender ID each month
# Options: 10, 100, 1,000, 10,000, 100,000, 1,000,000, 10,000,000+
MONTHLY_MESSAGE_VOLUME = ['10,000']
# At least one sample is required of an SMS message which will be sent from this sender ID
# Maximum 306 characters
MESSAGE_SAMPLE = 'Your OTP is XXX'
# India Specific Settings
# ----------------------
# Acknowledgement that you will specify Entity ID and Template ID when sending messages
# This is REQUIRED and must be 'Yes'
SENDING_PARAMETERS_ACKNOWLEDGMENT = ['Yes']

The following script handles the creation of the registration, updating of India-specific fields, and submission of the registration. Save the following file as india_senderid_registration.py:

import boto3
from typing import Dict, Union, List
import logging
import importlib.util
import argparse
# Set up logging
logging.basicConfig(level=logging.INFO, format='%(asctime)s - %(levelname)s - %(message)s')
logger = logging.getLogger(__name__)
def load_config(config_file):
    """Load configuration from a Python file"""
    spec = importlib.util.spec_from_file_location("config", config_file)
    config = importlib.util.module_from_spec(spec)
    spec.loader.exec_module(config)
    return config
class EndUserMessagingRegistrationIndia:
    def __init__(self, config):
        self.client = boto3.client('pinpoint-sms-voice-v2',region_name=config.REGION_NAME)
        self.registration_id = None
        self.config = config
    def create_registration(self) -> str:
        """Create a new Sender ID registration"""
        try:
            response = self.client.create_registration(RegistrationType=self.config.REGISTRATION_TYPE,
                                                       Tags=[{'Key': 'Name', 'Value': self.config.REGISTRATION_NAME}])
            self.registration_id = response['RegistrationId']
            logger.info(f"Registration created with ID: {self.registration_id}")
            return self.registration_id
        except Exception as e:
            logger.error(f"Failed to create registration: {str(e)}")
            raise
    def update_registration_fields(self, fields: Dict[str, Union[str, List[str]]]):
        """Update registration fields with provided values"""
        if not self.registration_id:
            raise ValueError("Registration ID not set. Create registration first.")
for field_path, value in fields.items():
            try:
                if isinstance(value, list):
                    self.client.put_registration_field_value(
                        RegistrationId=self.registration_id,
                        FieldPath=field_path,
                        SelectChoices=value
                    )
                else:
                    self.client.put_registration_field_value(
                        RegistrationId=self.registration_id,
                        FieldPath=field_path,
                        TextValue=value
                    )
                logger.info(f"Updated field: {field_path}")
            except Exception as e:
                logger.error(f"Failed to update field {field_path}: {str(e)}")
                raise
    def submit_registration(self):
        """Submit the registration for review"""
        if not self.registration_id:
            raise ValueError("Registration ID not set. Create registration first.")
        try:
            self.client.submit_registration_version(RegistrationId=self.registration_id)
            logger.info("Registration submitted successfully")
        except Exception as e:
            logger.error(f"Failed to submit registration: {str(e)}")
            raise
def main():
    parser = argparse.ArgumentParser(description='SMS Registration Tool')
    parser.add_argument('--config', required=True, help='Path to config file')
    args = parser.parse_args()
    
    config = load_config(args.config)
    registration = EndUserMessagingRegistrationIndia(config)
    registration.create_registration()
    fields = {
        'senderIdInfo.senderId': config.SENDER_ID,
        'inSidSpecificInfo.principalEntityId': config.ENTITY_ID,
        'inSidSpecificInfo.chainId1': config.CHAIN_ID_1,
        'inSidSpecificInfo.chainId2': config.CHAIN_ID_2,
        'inSidSpecificInfo.chainId3': config.CHAIN_ID_3,
        'inSidSpecificInfo.chainId5': config.CHAIN_ID_5,
        'inSidSpecificInfo.sendingParametersAcknowledgement': config.SENDING_PARAMETERS_ACKNOWLEDGMENT,
        'companyInfo.companyId': config.COMPANY_ID,
        'companyInfo.companyName': config.COMPANY_NAME,
        'companyInfo.website': config.COMPANY_WEBSITE,
        'companyInfo.areaOfBusiness': config.AREA_OF_BUSINESS,
        'companyAddress.address1': config.COMPANY_ADDRESS,
        'companyAddress.city': config.COMPANY_CITY,
        'companyAddress.isoCountryCode': config.COUNTRY_CODE,
        'contactInfo.emailAddress': config.CONTACT_EMAIL,
        'contactInfo.phoneNumber': config.CONTACT_PHONE,
        'messagingUseCase.useCaseCategory': config.USE_CASE_CATEGORY,
        'messagingUseCase.useCaseDescription': config.USE_CASE_DESCRIPTION,
        'messagingUseCase.monthlyMessageVolume': config.MONTHLY_MESSAGE_VOLUME,
        'messagingUseCase.optInDescription': config.USE_CASE_DESCRIPTION,
        'messageSamples.messageSample1': config.MESSAGE_SAMPLE
    }
    registration.update_registration_fields(fields)
    registration.submit_registration()
if __name__ == "__main__":
    main()

Run the script: python india_senderid_registration.py --config india_config.py

After submission, you can monitor the registration status. Upon approval, the status will show as Complete, as shown in the following screenshot.

The following screenshot shows that the registration requires updates before it can be approved.

The error occurred because the registration code was run in an Region other than AP-SOUTH-1 or AP-SOUTH-2. To resolve this issue, delete the current registration and rerun the process in one of the supported Regions.

As mentioned earlier, DescribeRegistrationFieldDefinitions varies by country, because each has unique registration requirements and field specifications. You must modify this script according to your target country’s specific requirements. Refer to the API documentation for country-specific registration types and field definitions.

Check registration status

Check the status of your registration using either the AWS End User Messaging console or the DescribeRegistrations API. To use the console, choose Registrations under Configurations in the navigation pane.

The registration status for each request will initially display CREATED and will change to REVIEWING within 24 hours after submission. For more information about registration statuses, refer to Check a registration’s status in AWS End User Messaging SMS. If your registration status shows REQUIRES_UPDATES, the registration needs more information. You can edit and resubmit the request with the required information.

As noted earlier, third-party reviewers evaluate registrations. Expect 2-4 weeks for approval, and longer for sender IDs in some countries.

SMS program registrations for ISVs

Independent software vendors (ISVs) are positioned between AWS End User Messaging and the ISV’s end business customers. Though they might operate differently or offer different services, their requirements for SMS program registrations are largely the same. End business refers to your ISV customers. This is generally the entity that creates the messaging content, distributes it through your platform, and interacts with their end-users (message recipients).

SMS program registrations require end-user business information, not ISV information. This means the ISV must provide a mechanism for their end businesses to provide their information to be submitted for registration. ISVs and aggregators must provide information representing the customer entity sending messages to opted-in recipients. Amazon uses this information in accordance with all applicable obligations, and to verify the end-user is a legitimate business. Amazon will not contact the end-business user with the information provided.

Conclusion

In this post, we showed how to automate the sender ID registration process using Python scripts and AWS End User Messaging APIs. Using these APIs can significantly improve efficiency and reduce manual errors. For additional guidance, refer to automating AWS End User Messaging US Toll-Free Number registrations, Automate AWS End User Messaging US toll-free Number Registrations, How to Register a Sender ID Using APIs with AWS End User Messaging, and the AWS End User Messaging V2 API Reference.


About the authors

Amazon EMR Serverless eliminates local storage provisioning, reducing data processing costs by up to 20%

Post Syndicated from Karthik Prabhakar original https://aws.amazon.com/blogs/big-data/amazon-emr-serverless-eliminates-local-storage-provisioning-reducing-data-processing-costs-by-up-to-20/

At AWS re:Invent 2025, Amazon Web Services (AWS) announced serverless storage for Amazon EMR Serverless, a new capability that eliminates the need configure local disks for Apache Spark workloads. This reduces data processing costs by up to 20% while eliminating job failures from disk capacity constraints.

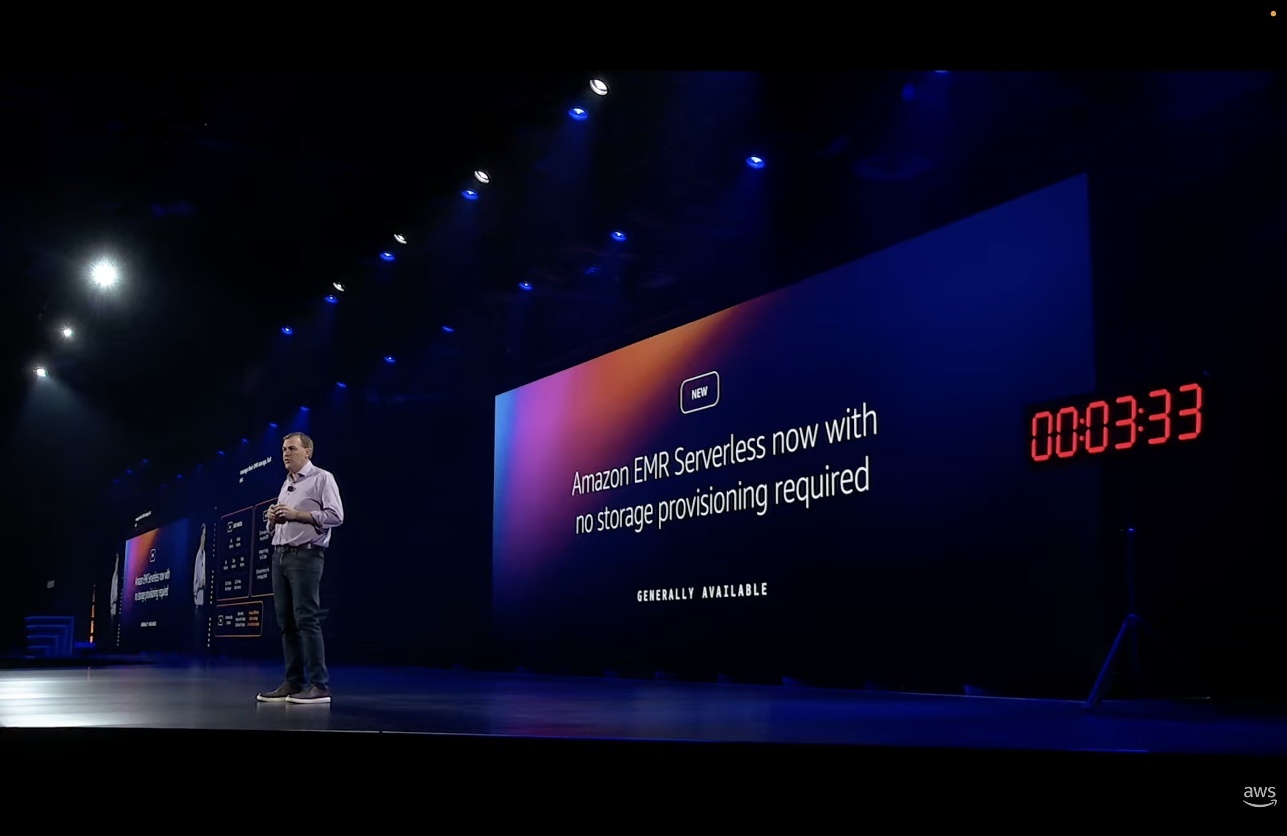
With serverless storage, Amazon EMR Serverless automatically handles intermediate data operations, such as shuffle, on your behalf. You pay only for compute and memory—no storage charges. By decoupling storage from compute, Spark can release idle workers immediately, reducing costs throughout the job lifecycle. The following image shows the serverless storage for EMR Serverless announcement from the AWS re:Invent 2025 keynote:

The challenge: Sizing local disk storage

Running Apache Spark workloads requires sizing local disk storage for shuffle operations—where Spark redistributes data across executors during joins, aggregations, and sorts. This requires analyzing job histories to estimate disk requirements, leading to two common problems: overprovisioning wastes money on unused capacity, and under provisioning causes job failures when disk space runs out. Most customers overprovision local storage to ensure jobs complete successfully in production.

Data skew compounds this further. When one executor handles a disproportionately large partition, that executor takes significantly longer to complete while other workers sit idle. If you didn’t provision enough disk for that skewed executor, the job fails entirely—making data skew one of the top causes of Spark job failures. However, the problem extends beyond capacity planning. Because shuffle data couples tightly to local disks, Spark executors pin to worker nodes even when compute requirements drop between job stages. This prevents Spark from releasing workers and scaling down, inflating compute costs throughout the job lifecycle. When a worker node fails, Spark must recompute the shuffle data stored on that node, causing delays and inefficient resource usage.

How it works

Serverless storage for Amazon EMR Serverless addresses these challenges by offloading shuffle operations from individual compute workers onto a separate, elastic storage layer. Instead of storing critical data on local disks attached to Spark executors, serverless storage automatically provisions and scales high-performance remote storage as your job runs.

The architecture provides several key benefits. First, compute and storage scale independently—Spark can acquire and release workers as needed across job stages without worrying about preserving locally stored data. Second, shuffle data is evenly distributed across the serverless storage layer, eliminating data skew bottlenecks that occur when some executors handle disproportionately large shuffle partitions. Third, if a worker node fails, your job continues processing without delays or reruns because data is reliably stored outside individual compute workers.

Serverless storage is provided at no additional charge, and it eliminates the cost associated with local storage. Instead of paying for fixed disk capacity sized for maximum potential I/O load—capacity that often sits idle during lighter workloads—you can use serverless storage without incurring storage costs. You can focus your budget on compute resources that directly process your data, not on managing and overprovisioning disk storage.

Technical innovation brings three breakthroughs

Serverless storage introduces three fundamental innovations that solve Spark’s shuffle bottlenecks: multi-tier aggregation architecture, purpose-built networking, and true storage-compute decoupling. Apache Spark’s shuffle mechanism has a core constraint: each mapper independently writes output as small files, and each reducer must fetch data from potentially thousands of workers. In a large-scale job with 10,000 mappers and 1,000 reducers, this creates 10 million individual data exchanges. Serverless storage aggregates early and intelligently—mappers stream data to an aggregation layer that consolidates shuffle data in memory before committing to storage. Whereas individual shuffle write and fetch operations might show slightly higher latency due to network round-trips compared to local disk I/O, the overall job performance improves by transforming millions of tiny I/O operations into a smaller number of large, sequential operations.

Traditional Spark shuffle creates a mesh network where each worker maintains connections to potentially hundreds of other workers, spending significant CPU on connection management rather than data processing. We built a custom networking stack where each mapper opens a single persistent remote procedure call (RPC) connection to our aggregator layer, eliminating the mesh complexity. Although individual shuffle operations might show slightly higher latency due to network round trips compared to local disk I/O, overall job performance improves through better resource utilization and elastic scaling. Workers no longer run a shuffle service—they focus entirely on processing your data.

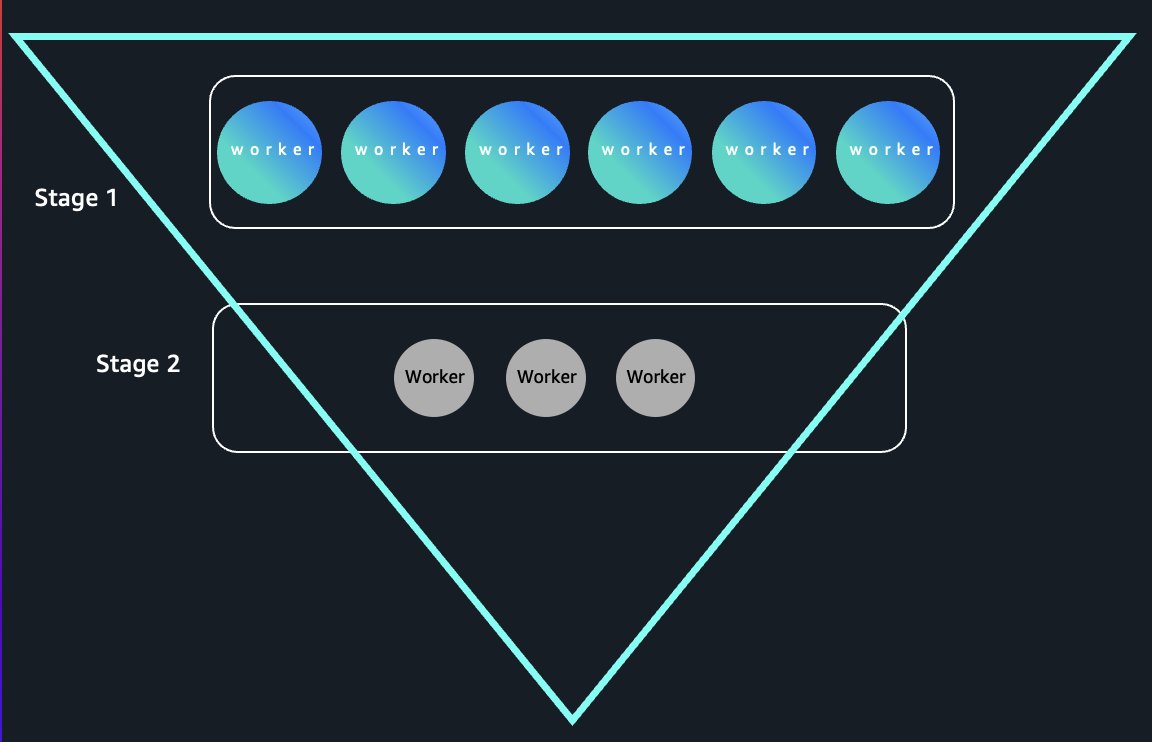
Traditional Amazon EMR Serverless jobs store shuffle data on local disks, coupling data lifecycle to worker lifecycle—idle workers can’t terminate without losing shuffle data. Serverless storage decouples these entirely by storing shuffle data in AWS managed storage with opaque handles tracked by the driver. Workers can terminate immediately after completing tasks without data loss, enabling elastic scaling. In funnel-shaped queries where early stages require massive parallelism that narrows as data aggregates, we’re seeing up to 80% compute cost reduction in benchmarks by releasing idle workers instantly. The following diagram illustrates instant worker release in funnel-shaped queries.

Our aggregator layer integrates directly with AWS Identity and Access Management (IAM), AWS Lake Formation, and fine-grained access control systems, providing job-level data isolation with access controls that match source data permissions.

Getting started

Serverless storage is available in multiple AWS Regions. For the current list of supported Regions, refer to the Amazon EMR User Guide.

New applications

Serverless storage can be enabled for new applications starting with Amazon EMR release 7.12. Follow these steps:

  1. Create an Amazon EMR Serverless application with Amazon EMR 7.12 or later:
aws emr-serverless create-application \
  --type "SPARK" \
  --name my-application \
  --release-label emr-7.12.0 \
  --runtime-configuration '[{
      "classification": "spark-defaults",
        "properties": {
          "spark.aws.serverlessStorage.enabled": "true"
        }
    }]' \
  --region us-east-1
  1. Submit your Spark job:
aws emr-serverless start-job-run \
  --application-id <application-id> \
  --execution-role-arn <execution-role-arn> \
  --job-driver '{
    "sparkSubmit": {
      "entryPoint": "s3://<bucket>/<your_script.py>",
      "sparkSubmitParameters": "--conf spark.executor.cores=4 --conf spark.executor.memory=20g --conf spark.driver.cores=4 --conf spark.driver.memory=8g --conf spark.executor.instances=10"
    }
  }'

Existing applications

You can enable serverless storage for existing applications on Amazon EMR 7.12 or later by updating your application settings.

To enable serverless storage using AWS Command Line Interface (AWS CLI), enter the following command:

aws emr-serverless update-application \
  --application-id <application-id> \
  --runtime-configuration '[{
      "classification": "spark-defaults",
        "properties": {
          "spark.aws.serverlessStorage.enabled": "true"
        }
    }]'

To enable serverless storage using Amazon EMR Studio UI, navigate to your application in Amazon EMR Studio, go to Configuration, and add the Spark property spark.aws.serverlessStorage.enabled=true in the spark-defaults classification.

Job-level configuration

You can also enable serverless storage for specific jobs, even when it’s not enabled at the application level:

aws emr-serverless start-job-run \
  --application-id <application-id> \
  --execution-role-arn <execution-role-arn> \
  --job-driver '{
    "sparkSubmit": {
      "entryPoint": "s3://<bucket>/<your_script.py>",
      "sparkSubmitParameters": "--conf spark.executor.cores=4 --conf spark.executor.memory=20g --conf spark.aws.serverlessStorage.enabled=true"
    }
  }'

(Optional) Disabling serverless storage

If you prefer to continue using local disks, you can disable serverless storage by omitting the spark.aws.serverlessStorage.enabled configuration or setting it to false at either the application or job level:

spark.aws.serverlessStorage.enabled=falseTo use traditional local disk provisioning, configure the appropriate disk type and size for your application workers.

Monitoring and cost tracking

You can monitor elastic shuffle usage through standard Spark UI metrics and track costs at the application level in AWS Cost Explorer and AWS Cost and Usage Reports. The service automatically handles performance optimization and scaling, so you don’t need to tune configuration parameters.

When to use serverless storage

Serverless storage delivers the most value for workloads with substantial shuffle operations—typically jobs that shuffle more than 10 GB of data (and less than 200 G per job, the limitation as of this writing). These include:

  • Large-scale data processing with heavy aggregations and joins
  • Sort-heavy analytics workloads
  • Iterative algorithms that repeatedly access the same datasets

Jobs with unpredictable shuffle sizes benefit particularly well because serverless storage automatically scales capacity up and down based on real-time demand. For workloads with minimal shuffle activity or very short duration (under 2–3 minutes), the benefits might be limited. In these cases, the overhead of remote storage access might outweigh the advantages of elastic scaling.

Security and data lifecycle

Your data is stored in serverless storage only while your job is running and is automatically deleted when your job is completed. Because Amazon EMR Serverless batch jobs can run for up to 24 hours, your data will be stored for no longer than this maximum duration. Serverless storage encrypts your data both in transit between your Amazon EMR Serverless application and the serverless storage layer and at rest while temporarily stored, using AWS managed encryption keys. The service uses an IAM based security model with job-level data isolation, which means that one job can’t access the shuffle data of another job. Serverless storage maintains the same security standards as Amazon EMR Serverless, with enterprise-grade security controls throughout the processing lifecycle.

Conclusion

Serverless storage represents a fundamental shift in how we approach data processing infrastructure, eliminating manual configuration, aligning costs to actual usage, and improving reliability for I/O intensive workloads. By offloading shuffle operations to a managed service, data engineers can focus on building analytics rather than managing storage infrastructure.

To learn more about serverless storage and get started, visit the Amazon EMR Serverless documentation.


About the authors

Karthik Prabhakar

Karthik Prabhakar

Karthik is a Data Processing Engines Architect for Amazon EMR at AWS. He specializes in distributed systems architecture and query optimization, working with customers to solve complex performance challenges in large-scale data processing workloads. His focus spans engine internals, cost optimization strategies, and architectural patterns that enable customers to run petabyte-scale analytics efficiently.

Ravi Kumar

Ravi Kumar

Ravi is a Senior Product Manager Technical at Amazon Web Services, specializing in exabyte-scale data infrastructure and analytics platforms. He helps customers unlock insights from structured and unstructured data using open-source technologies and cloud computing. Outside of work, Ravi enjoys exploring emerging trends in data science and machine learning.

Matt Tolton

Matt Tolton

Matt is a Senior Principal Engineer at Amazon Web Services.

author name

Neil Mukerje

Neil is a Principal Product Manager at Amazon Web Services.

How Taxbit achieved cost savings and faster processing times using Amazon S3 Tables

Post Syndicated from Larry Christensen original https://aws.amazon.com/blogs/big-data/how-taxbit-achieved-cost-savings-and-faster-processing-times-using-amazon-s3-tables/

In this post, we discuss how Taxbit partnered with Amazon Web Services (AWS) to streamline their crypto tax analytics solution using Amazon S3 Tables, achieving 82% cost savings and five times faster processing times.

Taxbit is a leading tax compliance suite serving cryptocurrency exchanges, digital platforms, and government agencies, generating more than 100 million forms for users and reconciling more than 500 billion digital asset transactions. The suite powers a complex environment that handles real-time pricing data from 29 cryptocurrency exchanges covering over 10,000 digital assets.

Recently, Taxbit experienced challenges with their pricing data infrastructure. As data volumes continued to expand, infrastructure costs rose sharply, putting pressure on operational budgets. At the same time, the system struggled to efficiently ingest the growing number of pricing data points, creating persistent bottlenecks in their data pipeline. These technical limitations led to customers missing data and experiencing slow processing times, leading to dissatisfaction. In addition to these operational challenges, Taxbit has strict regulatory compliance requirements to be considered when designing solutions. This combination of issues led Taxbit to modernize their pricing data infrastructure with a focus on helping to meet regulatory standards.

“During peak workloads, our solutions process hundreds of millions of digital asset transactions across blockchain and cryptocurrency exchanges,”

– says Clark Roberts, CTO at Taxbit.

“Our legacy database architecture was becoming a bottleneck, leading to increased costs and slower response times for our enterprise and government customers.”

Solution overview

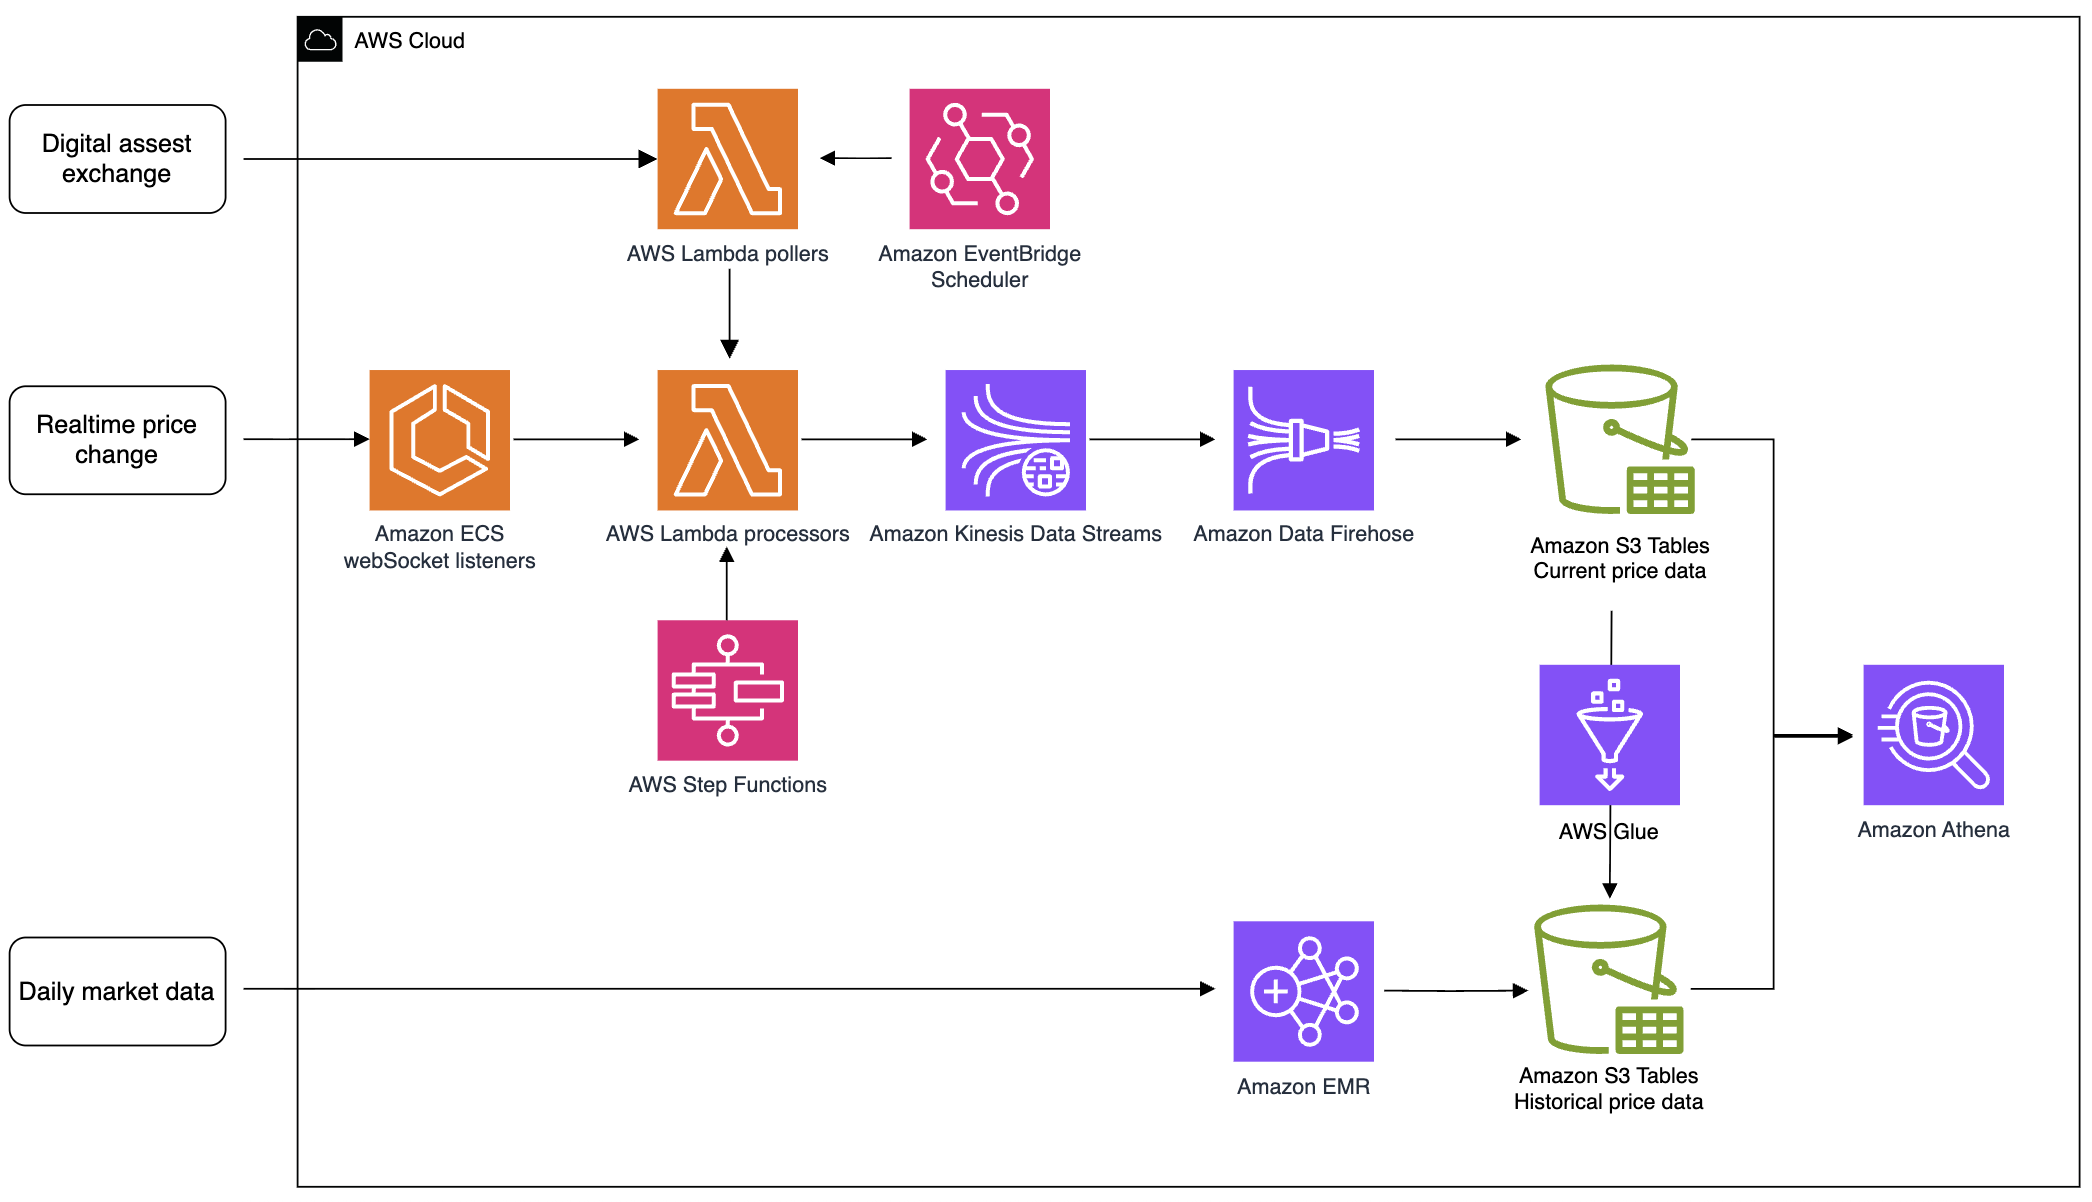
Taxbit’s modernized architecture uses Amazon S3 Tables with Apache Iceberg as the foundation, combined with purpose-built AWS services for data ingestion, processing, and analytics. The solution processes real-time pricing data from 29 cryptocurrency exchanges including over 10,000 digital assets. This architecture is shown in the following diagram.

This AWS cloud architecture diagram illustrates a comprehensive data pipeline for processing digital assest market data.

The data pipeline architecture uses AWS services to deliver a comprehensive solution. At its foundation, Amazon S3 Tables provides the scalable storage infrastructure necessary for managing large volumes of pricing data. For data processing and transformation, the solution combines Amazon EMR and AWS Glue, handling both extract, transform, and load (ETL) operations and asynchronous API requirements efficiently.

Real-time data handling is managed through Amazon Kinesis, enabling streaming of pricing updates. AWS Lambda functions perform multiple tasks, including periodic polling of vendor APIs, transformation of streaming data, and data enrichment. The orchestration of these components is managed by AWS Step Functions, helping to ensure coordination of data workflows. Completing the architecture, Amazon Athena provides query capabilities, supporting both synchronous APIs and one-time analytical queries. This approach creates a scalable system built to handle both real-time and batch processing workflows while maintaining high performance and reliability.

Data ingestion layer

The ingestion layer operates through two key components: API integration and stream processing. The API integration uses Lambda functions to systematically poll multiple external APIs. These polling operations are orchestrated by Amazon EventBridge, which manages the scheduled data collection tasks. Additionally, WebSocket listeners maintain continuous connections to capture real-time price updates as they occur.

On the stream processing side, Amazon Kinesis Data Streams serves as the backbone for handling real-time data ingestion at scale. As data flows in, Lambda functions perform transformations and enrichment operations to prepare the data for downstream use. Throughout this process, custom validation checks are applied to help ensure the quality and completeness of the data, helping to maintain the integrity of the pricing information pipeline.

Data storage layer

At the storage layer, Taxbit uses Amazon S3 Tables because of its optimized storage format designed for analytical queries. Amazon S3 Tables is designed to automatically handle table optimization and compaction, helping to streamline data management processes. The system also incorporates time-travel capabilities, allowing Taxbit to meet audit requirements and their need for historical data analysis.

The data organization strategy is designed to maximize efficiency and accessibility. Data is systematically partitioned by date and exchange, allowing for targeted data retrieval and improved query performance. The implementation of columnar storage further enhances query efficiency by minimizing unnecessary data scans. Additionally, version control mechanisms are in place to maintain clear data lineage, enabling precise tracking of data changes and transformations over time.

Analytics layer

At the analytics layer, the query engine forms the foundation, using Amazon Athena to facilitate flexible ad-hoc analysis of the pricing data. This is complemented by Presto-based queries that handle complex aggregations efficiently. The system includes carefully crafted execution plans optimized for common query patterns, designed to provide consistent and reliable performance.

To maximize efficiency, the analytics layer incorporates several key performance optimizations. The system uses an Athena reuse query result to minimize redundant processing and parallel query execution capabilities to handle multiple simultaneous requests effectively.

Security and compliance

The data protection strategy implements multiple layers of security, starting with AWS Key Management Service (AWS KMS) encryption for all data at rest. This is complemented by TLS encryption for data in transit, helping to secure data movement throughout the system. Access to data and resources is controlled through AWS Identity and Access Management (IAM), providing fine-grained permissions that enforce the principle of least privilege.

The audit trail component provides comprehensive monitoring and compliance capabilities. AWS CloudTrail logging captures detailed records of system activities, enabling thorough security analysis and incident investigation. Data lineage tracking maintains clear records of data movement and transformations throughout the pipeline. These features are augmented by robust compliance reporting capabilities, helping the system demonstrate adherence to regulatory requirements and internal governance policies. Together, these security controls create an environment that protects sensitive data, maintains transparency, and provides accountability.

Business impact

Most notably, Taxbit achieved an 82% reduction in storage infrastructure costs, while simultaneously delivering processing speeds five times faster than their previous architecture. Data completeness for calculations achieved approximately 99.99% accuracy and the workload can now successfully support over 10,000 digital assets.The benefits extended beyond these quantitative improvements. Customer experience has improved, with transaction pricing times shrinking from hours to minutes. Higher throughput capabilities increased operational efficiency, enabling faster data loading while reducing compute costs. The new architecture also established a scalable foundation that provides faster data access and the flexibility to expand into new markets. The modern infrastructure has also enabled Taxbit to pursue new product offerings by supporting advanced analytics and real-time insights that were previously unattainable. These capabilities created new business opportunities and revenue streams that weren’t possible under the constraints of the legacy system.

Conclusion

Taxbit’s implementation of Amazon S3 Tables has transformed their cryptocurrency tax compliance solutions, delivering 82% cost savings and five times faster processing speeds. The modernized architecture, combining Amazon EMR, AWS Glue, Amazon Kinesis, and Lambda, now processes transactions in minutes instead of hours. Additionally, the architecture has helped Taxbit maintain approximately 99.99% data accuracy across more than 10,000 digital assets. Beyond operational improvements, this transformation has enabled new product offerings and real-time analytics capabilities. By partnering with AWS, Taxbit addressed their scaling challenges and built a foundation for continued innovation in the digital asset space.

For more information, see Amazon S3 Tables.


About the authors

Larry Christensen

Larry Christensen

Larry is a Principal Engineer at Taxbit based in the Salt Lake City area. He’s spearheaded many architectural, big data, and AI transformations across Taxbit.

Washim Nawaz

Washim Nawaz

Washim is an Analytics Specialist Solutions Architect at AWS with extensive professional experience building and tuning data warehouse and data lake solutions. He is passionate about helping customers modernize their data platforms with efficient, performant, and scalable analytics solutions. Outside of work, he enjoys watching sports and traveling.

Derek Ziehl

Derek Ziehl

Derek is a Senior Technical Account Manager (TAM) at AWS. He has a background designing large-scale network systems and managing cloud migrations. As a TAM he enjoys enabling customers to run resilient, optimized workloads on AWS.

Pranjal Gururani

Pranjal Gururani

Pranjal is a Solutions Architect at AWS based out of Seattle. Pranjal works with various customers to architect cloud solutions that address their business challenges. He enjoys hiking, kayaking, skydiving, and spending time with family during his spare time.

Security Hub CSPM automation rule migration to Security Hub

Post Syndicated from Joe Wagner original https://aws.amazon.com/blogs/security/security-hub-cspm-automation-rule-migration-to-security-hub/

A new version of AWS Security Hub is now generally available with new capabilities to aggregate, correlate, and contextualize your security alerts across Amazon Web Services (AWS) accounts. The prior version is now known as AWS Security Hub CSPM and will continue to be available as a unique service focused on cloud security posture management and finding aggregation.

One capability available in both services is automation rules. In both Security Hub and Security Hub CSPM, you can use automation rules to automatically update finding fields when the criteria they define are met. In Security Hub, automation rules can be used to send findings to third-party platforms for operational response. Many existing Security Hub CSPM users have automation rules for tasks such as elevating the severity of a finding because it affects a production resource or adding a comment to assist in remediation workflows. While both services offer similar automation rule functionality, rules aren’t synchronized across the two services. If you are an existing Security Hub CSPM customer looking to adopt the new Security Hub, you might be interested in migrating the automation rules that have already been built. This helps keep your automation rules processing close to where you’re reviewing findings. As of publication, this capability is included in the cost of the Security Hub essentials plan. For current pricing details, refer to the Security Hub pricing page.

This post provides a solution to automatically migrate automation rules from Security Hub CSPM to Security Hub, helping you maintain your security automation workflows while taking advantage of the new Security Hub features. If you aren’t currently using automation rules and want to get started, see Automation rules in Security Hub.

Automation rule migration challenge

Security Hub CSPM uses the AWS Security Finding Format (ASFF) as the schema for its findings. This schema is fundamental to how automation rules are applied to findings as they are generated. Automation rules begin by defining one or more criteria and then selecting one or more actions that will be applied when the specified criteria are met. Each criterion specifies an ASFF field, an operator (such as equals or contains), and a value. Actions then update one or more ASFF fields.

The new version of Security Hub uses the Open Cybersecurity Schema Framework (OCSF), a widely adopted open-source schema supported by AWS and partners in the cybersecurity industry. Security Hub automation rules structurally work the same way as Security Hub CSPM rules. However, the underlying schema change means existing automation rules require transformation.

The solution provided in this post automatically discovers Security Hub CSPM automation rules, transforms them into the OCSF schema, and creates an AWS CloudFormation template that you can use to deploy them to your AWS account running the new version of Security Hub. Because of inherent differences between the ASFF and OCSF schemas, some rules can’t be automatically migrated, while others might require manual review after migration.

The following table show the current mapping between ASFF fields supported as criteria and their corresponding OCSF fields. These mappings may change in future service releases. Fields marked as N/A can’t be migrated and will require special consideration when migrating automation rules. They need to be redesigned in the new Security Hub. The solution provided in this post is designed to skip migration of rules with one or more ASFF criteria that don’t map to an OCSF field but will identify those rules in a report for your review.

Rule criterion in ASFF Corresponding OCSF field
AwsAccountId cloud.account.uid
AwsAccountName  cloud.account.name
CompanyName  metadata.product.vendor_name 
ComplianceAssociatedStandardsId compliance.standards
ComplianceSecurityControlId  compliance.control 
ComplianceStatus  compliance.status 
Confidence  confidence_score
CreatedAt  finding_info.created_time 
Criticality  N/A
Description  finding_info.desc 
FirstObservedAt  finding_info.first_seen_time
GeneratorId  N/A
Id  finding_info.uid 
 LastObservedAt finding_info.last_seen_time 
 NoteText comment 
NoteUpdatedAt  N/A
NoteUpdatedBy  N/A
ProductArn  metadata.product.uid 
ProductName  metadata.product.name 
RecordState  activity_name 
RelatedFindingsId  N/A
RelatedFindingsProductArn  N/A
ResourceApplicationArn  N/A
ResourceApplicationName  N/A
ResourceDetailsOther  N/A
ResourceId  resources[x].uid 
ResourcePartition  resources[x].cloud_partition 
ResourceRegion  resources[x].region 
ResourceTags  resources[x].tags 
ResourceType  resources[x].type 
SeverityLabel  vendor_attributes.severity 
SourceUrl  finding_info.src_url 
Title  finding_info.title 
Type  finding_info.types 
UpdatedAt  finding_info.modified_time 
UserDefinedFields  N/A
VerificationState  N/A
WorkflowStatus  status 

The following table shows the ASFF fields that are supported as actions and their corresponding OCSF fields. Note that several action fields aren’t available in OCSF:

Rule action fields in ASFF Corresponding OCSF field
Confidence  N/A
Criticality  N/A
Note  Comment 
RelatedFindings  N/A
Severity  Severity 
Types  N/A
UserDefinedFields  N/A
VerificationState  N/A
Workflow Status  Status 

For Security Hub CSPM automation rules that include actions without OCSF equivalents, the solution is designed to migrate the rules but include only the supported actions. These rules will be designated as partially migrated in the rule description and the migration report. You can use this information to review and modify the rules before enabling them, helping to ensure that the new automation rules behave as expected.

Solution overview

This solution provides a set of Python scripts designed to assist with the migration of automation rules from Security Hub CSPM to the new Security Hub. Here’s how the migration process works:

  1. Begin migration: The solution provides an orchestration script that initiates three sub-scripts and manages passing the proper inputs to them.
  2. Discovery: The solution scans your Security Hub CSPM environment to identify and collect existing automation rules across specified AWS Regions.
  3. Analysis: Each rule is evaluated to determine if it can be fully migrated, partially migrated, or requires manual intervention based on ASFF to OCSF field mapping compatibility.
  4. Transformation: Compatible rules are automatically converted from the ASFF schema to the OCSF schema using predefined field mappings.
  5. Template creation: The solution generates a CloudFormation template containing the transformed rules, maintaining their original order and Regional context.
  6. Deployment: Review the generated template and deploy it to create the migrated rules in Security Hub, where they are created in a disabled state by default.
  7. Validate and enable rules: Review each migrated rule in the AWS Management Console for Security Hub to verify its criteria, actions, and preview your current matching findings if applicable. After confirming that the rules work as intended individually and as a sequence, enable them to resume your automation workflows.
Figure 1: Architecture diagram showing scripts and how they interact with AWS

Figure 1: Architecture diagram showing scripts and how they interact with AWS

The solution, shown in Figure 1, consists of four Python scripts that work together to migrate your automation rules:

  1. Orchestrator: Coordinates discovery, transformation, and generation along with reporting and logging
  2. Rule discovery: Identifies and extracts existing automation rules from Security Hub CSPM across the Regions you specify
  3. Schema transformation: Converts the rules from ASFF to OCSF format using the field mapping detailed earlier
  4. Template generation: Creates CloudFormation templates that you can use to deploy the migrate rules

The scripts use credentials configured using the AWS Command Line Interface (AWS CLI) to discover existing Security Hub automation rules. For details on how to configure credentials using AWS CLI, see Setting up the AWS CLI.

Prerequisites

Before running the solution, ensure you have the following components and permissions in place.

  • Required software:
    • AWS CLI (latest version)
    • Python 3.12 or later
    • Python packages:
      • boto3 (latest version)
      • pyyaml (latest version)
  • Required permissions:
    For rule discovery and transformation:

    • securityhub:ListAutomationRules
    • securityhub:BatchGetAutomationRules
    • securityhub:GetFindingAggregator
    • securityhub:DescribeHub
    • securityhub:ListAutomationRulesV2

    For template deployment:

    • cloudformation:CreateStack
    • cloudformation:UpdateStack
    • cloudformation:DescribeStacks
    • cloudformation:CreateChangeSet
    • cloudformation:DescribeChangeSet
    • cloudformation:ExecuteChangeSet
    • cloudformation:GetTemplateSummary
    • securityhub:CreateAutomationRuleV2
    • securityhub:UpdateAutomationRuleV2
    • securityhub:DeleteAutomationRuleV2
    • securityhub:GetAutomationRuleV2
    • securityhub:TagResource
    • securityhub:ListTagsForResource

AWS account configuration

Security Hub supports a delegated administrator account model when used with AWS Organizations. This delegated administrator account centralizes the management of security findings and service configuration across your organization’s member accounts. Automation rules must be created in the delegated administrator account in the home Region, and in unlinked Regions. Member accounts can’t create their own automation rules.

We recommend using the same account as the delegated administrator for Security Hub CSPM and Security Hub to maintain consistent security management. Configure your AWS CLI with credentials for this delegated administrator account before running the migration solution (see Setting up the AWS CLI for more information).

While this solution is primarily designed for delegated administrator deployments, it also supports single-account Security Hub implementations.

Key migration concepts

Before proceeding with the migration of your automation rules from Security Hub CSPM to Security Hub, it’s important to understand several key concepts that affect how rules are migrated and deployed. These concepts influence the migration process and the resulting behavior of your rules. Understanding them will help you plan your migration strategy and validate the results effectively.

Default rule state

By default, migrated rules are created in a DISABLED state, meaning the actions will not be applied to findings as they are generated. The solution can optionally create rules in an ENABLED state, but this is not recommended. Instead, create the rules in a DISABLED state, review each rule, preview matching findings, and then move the rule to an ENABLED state when ready.

Unsupported fields

The migration report details any rules that can’t be migrated because they include one or more Security Hub CSPM criteria that aren’t supported by the new Security Hub. These cases occur because of the differences between the ASFF and OCSF schemas. These rules require special attention because they can’t be automatically replicated with equivalent behavior. This is particularly important if you have Security Hub CSPM rules that depend on priority order.

When rules have actions that aren’t supported, they will still be migrated if at least one action is supported. Rules with partially supported actions are flagged in the migration report and the new automation rule description and should be reviewed.

Home and linked Regions

Both Security Hub CSPM and Security Hub support a home Region that aggregates findings from linked Regions. However, their automation rules behave differently. Security Hub CSPM automation rules operate on a Regional basis. This means they only affect findings generated in the Region where they are created. Even if you use a home Region, Security Hub CSPM automation rules do not apply to the findings aggregated from linked Regions in the home Region. Security Hub supports automation rules defined in a home Region and applied to all linked Regions, and does not support the creation of automation rules in linked Regions. However, in Security Hub, unlinked Regions can still have their own automation rules that will affect only the findings generated in that Region. Unlinked Regions will need to have automation rules applied separately

The solution supports two deployment modes to handle these differences. The first mode, called Home Region, should be used for Security Hub deployments with a home Region enabled. This mode identifies Security Hub CSPM automation rules from specified Regions and then recreates them with an additional criteria to account for the Region the rule came from. Then, one CloudFormation template is generated that can be deployed in the home Region. The automation rules will still operate as intended because of the addition of the criteria for the original Region where it was created.

The second mode is called Region-by-Region. This mode is for users who don’t currently use a home Region. In this mode, the solution still discovers automation rules in the Regions specified but generates a unique CloudFormation template for each Region. The resulting templates can then be deployed one by one to the delegated administrator account for their corresponding Region. No additional criteria are added to the automation rule in this mode.

It is possible to use a home Region with Security Hub and link some Regions, but not all. If this is the case, run the Home Region mode for the home Region and all linked Regions. Then, re-run the solution in Region-by-Region mode for all unlinked Regions.

Rule order

Both Security Hub CSPM and Security Hub automation rules have an order in which they are evaluated. This can be important for certain situations where different automation rules might apply to the same findings or take actions on the same fields. This solution preserves the original order of your automation rules.

If there are existing Security Hub automation rules, the solution creates the new automation rules beginning after the existing rules. For example, if you have 3 Security Hub automation rules and are migrating 10 new rules, the solution will assign orders 4 through 13 to the new rules.

When using the Home Region mode, the order of automation rules for each Region is preserved and clustered together in the final order. For example, if a user with three Security Hub automation rules in three different Regions migrates the rules, they will be migrated sequentially. The solution will first migrate all rules from Region 1 in their original order, followed by all rules from Region 2 in their original order, and finally all rules from Region 3 in their original order.

Deploy and validate the migration

Now that you have the prerequisites in place and understand the basic concepts, you’re ready to deploy and validate the migration.

To deploy the migration:

1. Clone the Security Hub automation rules Migration Tool from the AWS samples GitHub repository:

git clone https://github.com/aws-samples/sample-SecurityHub-Automation-Rule-Migration.git

2. Run the scripts following the instructions of the README file, which will contain the most up-to-date implementation instructions. This will generate a CloudFormation template that will create the new Security Hub automation rules. Deploy the CloudFormation template using the AWS CLI or console. For more details, see the Create a stack from the CloudFormation console or the README file.

When deployment is complete, you can use the Security Hub console to review your migrated automation rules. Remember that rules are created in a DISABLED state by default. Review each rule’s criteria and actions carefully, checking that they match your intended automation workflow. You can also preview what existing findings would have matched each automation rule in the console.

To review and validate migrated rules:

1. Go to the Security Hub console and choose Automations from the navigation pane.

Figure 2: Security Hub Automations page

Figure 2: Security Hub Automations page

2. Select a rule and then choose Edit at the top of the page.

Figure 3: Security Hub automation rule details

Figure 3: Security Hub automation rule details

3. Choose Preview matching findings. It’s possible that no findings will be returned even if the automation rule is behaving as expected. This means only that there are currently no findings matching the rule criteria in Security Hub. In this case, you can still review the rule criteria.

Figure 4: Security Hub Edit automation rule page

Figure 4: Security Hub Edit automation rule page

4. After validating a rule’s configuration, you can enable it through the console from the rule editing page. You can also update the CloudFormation stack. If you didn’t need to change any criteria or actions of your automation rules, you can re-run the scripts with the optional —create-enabled flag to reproduce the CloudFormation template with all rules enabled and deploy it as an update to the existing stack.

Pay attention to any rules that have partially migrated actions, which will be noted in the Description of each rule. This means one or more actions from the original rule in Security Hub CSPM aren’t supported in Security Hub and the rule might behave differently than intended. The solution also produces a migration report that includes which rules were partially migrated and specifies which actions from the original rule could not be migrated. Review these rules carefully because they might behave differently than expected and need to be modified or recreated.

Figure 5: Review the descriptions of partially migrated automation rules

Figure 5: Review the descriptions of partially migrated automation rules

Conclusion

The new AWS Security Hub provides enhanced capabilities for aggregating, correlating, and contextualizing your security findings. While the schema change from ASFF to OCSF brings improved interoperability and integration options, it requires existing automation rules to be migrated. The solution provided in this post helps automate this migration process through discovering your existing rules, transforming them to the new schema, and generating CloudFormation templates that preserve rule order and Regional context.

After migrating your automation rules, start by reviewing the migration report to identify any rules that weren’t fully migrated. Pay special attention to rules marked as partially migrated, because these might behave differently than their original versions. We recommend testing each rule in a disabled state and validating that rules work together as expected—especially rules that operate on the same fields—before enabling them in your environment.

To learn more about Security Hub and its enhanced capabilities, see the Security Hub User Guide.
If you have feedback about this post, submit comments in the Comments section below.

Joe Wagner

Joe Wagner

Joe is a Senior Security Specialist Solutions Architect who focuses on AWS security services. He loves that cybersecurity is always changing and takes pride in helping his customers navigate it all. Outside of work, you’ll find him trying new hobbies, exploring local restaurants, and getting outside as much as he can.

Ahmed Adekunle

Ahmed Adekunle

Ahmed is a Security Specialist Solutions Architect focused on detection and response services at AWS. Before AWS, his background was in business process management and AWS tech consulting, helping customers use cloud technology to transform their business. Outside of work, Ahmed enjoys playing soccer, supporting less privileged activities, traveling, and eating spicy food, specifically African cuisine.

Salifu (Sal) Ceesay

Salifu (Sal) Ceesay

Sal is a Technical Account Manager at Amazon Web Services (AWS) specializing in financial services. He partners with organizations to operationalize and optimize managed solutions across many use cases, with expertise in native incident detection and response services. Beyond his professional pursuits, Sal enjoys gardening, playing and watching soccer, traveling, and participating in various outdoor activities with his family.

Power data ingestion into Splunk using Amazon Data Firehose

Post Syndicated from Tarik Makota original https://aws.amazon.com/blogs/big-data/power-data-ingestion-into-splunk-using-amazon-data-firehose/

Last updated: December 17, 2025


Originally published: December 18, 2017

Amazon Data Firehose supports Splunk Enterprise and Splunk Cloud as a delivery destination. This native integration between Splunk Enterprise, Splunk Cloud, and Amazon Data Firehose is designed to make AWS data ingestion setup seamless, while offering a secure and fault-tolerant delivery mechanism. We want to enable customers to monitor and analyze machine data from any source and use it to deliver operational intelligence and optimize IT, security, and business performance.

With Amazon Data Firehose, customers can use a fully managed, reliable, and scalable data streaming solution to Splunk. In this post, we tell you a bit more about the Amazon Data Firehose and Splunk integration. We also show you how to ingest large amounts of data into Splunk using Amazon Data Firehose.

Push vs. Pull data ingestion

Presently, customers use a combination of two ingestion patterns, primarily based on data source and volume, in addition to existing company infrastructure and expertise:

  1. Pull-based approach: Using dedicated pollers running the popular Splunk Add-on for AWS to pull data from various AWS services such as Amazon CloudWatch or Amazon S3.
  2. Push-based approach: Streaming data directly from AWS to Splunk HTTP Event Collector (HEC) by using Amazon Data Firehose. Examples of applicable data sources include CloudWatch Logs and Amazon Kinesis Data Streams.

The pull-based approach offers data delivery guarantees such as retries and checkpointing out of the box. However, it requires more ops to manage and orchestrate the dedicated pollers, which are commonly running on Amazon EC2 instances. With this setup, you pay for the infrastructure even when it’s idle.

On the other hand, the push-based approach offers a low-latency scalable data pipeline made up of serverless resources like Amazon Data Firehose sending directly to Splunk indexers (by using Splunk HEC). This approach translates into lower operational complexity and cost. However, if you need guaranteed data delivery then you have to design your solution to handle issues such as a Splunk connection failure or Lambda execution failure. To do so, you might use, for example, AWS Lambda Dead Letter Queues.

How about getting the best of both worlds?

Let’s go over the new integration’s end-to-end solution and examine how Amazon Data Firehose and Splunk together expand the push-based approach into a native AWS solution for applicable data sources.

By using a managed service like Amazon Data Firehose for data ingestion into Splunk, we provide out-of-the-box reliability and scalability. One of the pain points of the old approach was the overhead of managing the data collection nodes (Splunk heavy forwarders). With the new Amazon Data Firehose to Splunk integration, there are no forwarders to manage or set up. Data producers (1) are configured through the AWS Management Console to drop data into Amazon Data Firehose.

You can also create your own data producers. For example, you can drop data into a Firehose delivery stream by using Amazon Kinesis Agent, or by using the Firehose API (PutRecord(), PutRecordBatch()), or by writing to a Kinesis Data Stream configured to be the data source of a Firehose delivery stream. For more details, refer to Sending Data to an Amazon Data Firehose Delivery Stream.

You might need to transform the data before it goes into Splunk for analysis. For example, you might want to enrich it or filter or anonymize sensitive data. You can do so using AWS Lambda and enabling data transformation in Amazon Data Firehose. In this scenario, Amazon Data Firehose is used to decompress the Amazon CloudWatch logs by enabling the feature.

Systems fail all the time. Let’s see how this integration handles outside failures to guarantee data durability. In cases when Amazon Data Firehose can’t deliver data to the Splunk Cluster, data is automatically backed up to an S3 bucket. You can configure this feature while creating the Firehose delivery stream (2). You can choose to back up all data or only the data that’s failed during delivery to Splunk.

In addition to using S3 for data backup, this Firehose integration with Splunk supports Splunk Indexer Acknowledgments to guarantee event delivery. This feature is configured on Splunk’s HTTP Event Collector (HEC) (3). It ensures that HEC returns an acknowledgment to Amazon Data Firehose only after data has been indexed and is available in the Splunk cluster (4).

Now let’s look at a hands-on exercise that shows how to forward VPC flow logs to Splunk.

How-to guide

To process VPC flow logs, we implement the following architecture.

Amazon Virtual Private Cloud (Amazon VPC) delivers flow log files into an Amazon CloudWatch Logs group. Using a CloudWatch Logs subscription filter, we set up real-time delivery of CloudWatch Logs to an Amazon Data Firehose stream.

Data coming from CloudWatch Logs is compressed with gzip compression. To work with this compression, we will enable decompression for the Firehose stream. Firehose then delivers the raw logs to the Splunk Http Event Collector (HEC).

If delivery to the Splunk HEC fails, Firehose deposits the logs into an Amazon S3 bucket. You can then ingest the events from S3 using an alternate mechanism such as a Lambda function.

When data reaches Splunk (Enterprise or Cloud), Splunk parsing configurations (packaged in the Splunk Add-on for Amazon Data Firehose) extract and parse all fields. They make data ready for querying and visualization using Splunk Enterprise and Splunk Cloud.

Walkthrough

Install the Splunk Add-on for Amazon Data Firehose

The Splunk Add-on for Amazon Data Firehose enables Splunk (be it Splunk Enterprise, Splunk App for AWS, or Splunk Enterprise Security) to use data ingested from Amazon Data Firehose. Install the Add-on on all the indexers with an HTTP Event Collector (HEC). The Add-on is available for download from Splunkbase. For troubleshooting assistance, please refer to: AWS Data Firehose troubleshooting documentation & Splunk’s official troubleshooting guide

HTTP Event Collector (HEC)

Before you can use Amazon Data Firehose to deliver data to Splunk, set up the Splunk HEC to receive the data. From Splunk web, go to the Setting menu, choose Data Inputs, and choose HTTP Event Collector. Choose Global Settings, ensure All tokens is enabled, and then choose Save. Then choose New Token to create a new HEC endpoint and token. When you create a new token, make sure that Enable indexer acknowledgment is checked.

When prompted to select a source type, select aws:cloudwatchlogs:vpcflow

Create an S3 backsplash bucket

To provide for situations in which Amazon Data Firehose can’t deliver data to the Splunk Cluster, we use an S3 bucket to back up the data. You can configure this feature to back up all data or only the data that’s failed during delivery to Splunk.

Note: Bucket names are unique.

aws s3 create-bucket --bucket <your-s3-bucket-name> --create-bucket-configuration LocationConstraint=<your-region>

Create an Amazon Data Firehose delivery stream

On the AWS console, open the Amazon Data Firehose console, and choose Create Firehose Stream.

Select DirectPUT as the source and Splunk as the destination.

Create Firehose Stream

If you are using Firehose to deliver CloudWatch Logs and want to deliver decompressed data to your Firehose stream destination, use Firehose Data Format Conversion (Parquet, ORC) or Dynamic partitioning. You must enable decompression for your Firehose stream, check out Deliver decompressed Amazon CloudWatch Logs to Amazon S3 and Splunk using Amazon Data Firehose

Enter your Splunk HTTP Event Collector (HEC) information in destination settings

Firehose Destination setting

Note: Amazon Data Firehose requires the Splunk HTTP Event Collector (HEC) endpoint to be terminated with a valid CA-signed certificate matching the DNS hostname used to connect to your HEC endpoint. You receive delivery errors if you are using a self-signed certificate.

In this example, we only back up logs that fail during delivery.

Backsplash S3 settings

To monitor your Firehose delivery stream, enable error logging. Doing this means that you can monitor record delivery errors. Create an IAM role for the Firehose stream by choosing Create new, or Choose existing IAM role.

Advance settings for cloudwatch loggings

You now get a chance to review and adjust the Firehose stream settings. When you are satisfied, choose Create Firehose Stream.

Create a VPC Flow Log

To send events from Amazon VPC, you need to set up a VPC flow log. If you already have a VPC flow log you want to use, you can skip to the “Publish CloudWatch to Amazon Data Firehose” section.

On the AWS console, open the Amazon VPC service. Then choose VPC, and choose the VPC you want to send flow logs from. Choose Flow Logs, and then choose Create Flow Log. If you don’t have an IAM role that allows your VPC to publish logs to CloudWatch, choose Create and use a new service role.

VPC Flow Logs Settings

Once active, your VPC flow log should look like the following.

Flow logs

Publish CloudWatch to Amazon Data Firehose

When you generate traffic to or from your VPC, the log group is created in Amazon CloudWatch. We create an IAM role to allow Cloudwatch to publish logs to the Amazon Data Firehose Stream.

To allow CloudWatch to publish to your Firehose stream, you need to give it permissions.

$ aws iam create-role --role-name CWLtoFirehoseRole --assume-role-policy-document file://TrustPolicyForCWLToFireHose.json


Here is the content for TrustPolicyForCWLToFireHose.json.

{
  "Statement": {
    "Effect": "Allow",
    "Principal": { "Service": "logs.us-east-1.amazonaws.com" },
    "Action": "sts:AssumeRole"
  }
}

Attach the policy to the newly created role.

$ aws iam put-role-policy 
    --role-name CWLtoFirehoseRole 
    --policy-name Permissions-Policy-For-CWL 
    --policy-document file://PermissionPolicyForCWLToFireHose.json

Here is the content for PermissionPolicyForCWLToFireHose.json.

{
    "Statement":[
      {
        "Effect":"Allow",
        "Action":["firehose:*"],
        "Resource":["arn:aws:firehose:us-east-1:YOUR-AWS-ACCT-NUM:deliverystream/FirehoseSplunkDeliveryStream"]
      },
      {
        "Effect":"Allow",
        "Action":["iam:PassRole"],
        "Resource":["arn:aws:iam::YOUR-AWS-ACCT-NUM:role/CWLtoFirehoseRole"]
      }
    ]
}

The new log group has no subscription filter, so set up a subscription filter. Setting this up establishes a real-time data feed from the log group to your Firehose delivery stream. Select the VPC flow log and choose Actions. Then choose Subscription filters followed by Create Amazon Data Firehose subscription filter.

Subscription Filter option

Subscription filter details

When you run the AWS CLI command preceding, you don’t get any acknowledgment. To validate that your CloudWatch Log Group is subscribed to your Firehose stream, check the CloudWatch console.

As soon as the subscription filter is created, the real-time log data from the log group goes into your Firehose delivery stream. Your stream then delivers it to your Splunk Enterprise or Splunk Cloud environment for querying and visualization. The screenshot following is from Splunk Enterprise.

In addition, you can monitor and view metrics associated with your delivery stream using the AWS console.

Conclusion

Although our walkthrough uses VPC Flow Logs, the pattern can be used in many other scenarios. These include ingesting data from AWS IoT, other CloudWatch logs and events, Kinesis Streams or other data sources using the Kinesis Agent or Kinesis Producer Library. You may use a Lambda blueprint or disable record transformation entirely depending on your use case. For an additional use case using Amazon Data Firehose, check out This is My Architecture Video, which discusses how to securely centralize cross-account data analytics using Kinesis and Splunk.

If you found this post useful, be sure to check out Integrating Splunk with Amazon Kinesis Streams.


About the Authors

Tarik Makota

Tarik Makota

Tarik is a solutions architect with the Amazon Web Services Partner Network. He provides technical guidance, design advice and thought leadership to AWS’ most strategic software partners. His career includes work in an extremely broad software development and architecture roles across ERP, financial printing, benefit delivery and administration and financial services. He holds an M.S. in Software Development and Management from Rochester Institute of Technology.

Roy Arsan

Roy Arsan

Roy is a solutions architect in the Splunk Partner Integrations team. He has a background in product development, cloud architecture, and building consumer and enterprise cloud applications. More recently, he has architected Splunk solutions on major cloud providers, including an AWS Quick Start for Splunk that enables AWS users to easily deploy distributed Splunk Enterprise straight from their AWS console. He’s also the co-author of the AWS Lambda blueprints for Splunk. He holds an M.S. in Computer Science Engineering from the University of Michigan.

Yashika Jain

Yashika Jain

Yashika is a Senior Cloud Analytics Engineer at AWS, specializing in real-time analytics and event-driven architectures. She is committed to helping customers by providing deep technical guidance, driving best practices across real-time data platforms and solving complex issues related to their streaming data architectures.

Mitali Sheth

Mitali Sheth

Mitali is a Streaming Data Engineer in the AWS Professional Services team, specializing in real-time analytics and event-driven architectures for AWS’ most strategic software customers. More recently, she has focused on data governance with AWS Lake Formation, building reliable data pipelines with AWS Glue, and modernizing streaming infrastructure with Amazon MSK and Amazon Managed Flink for large-scale enterprise deployments. She holds an M.S. in Computer Science from the University of Florida.

Accelerate Apache Hive read and write on Amazon EMR using enhanced S3A

Post Syndicated from Ramesh Kandasamy original https://aws.amazon.com/blogs/big-data/accelerate-apache-hive-read-and-write-on-amazon-emr-using-enhanced-s3a/

Improving Apache Hive read and write performance on Amazon EMR is crucial for organizations dealing with large-scale data analytics and processing. When queries execute faster, businesses can make data-driven decisions more quickly, reduce time-to-insight, and optimize their operational costs. In today’s competitive landscape, where real-time analytics and interactive querying are becoming standard requirements, every millisecond of latency reduction can significantly impact business outcomes.

The Amazon EMR runtime for Apache Hive is a performance-optimized runtime that is 100% API compatible with open source Apache Hive. It offers faster out-of-the-box performance than Apache Hive through improved query plans, faster queries, and tuned defaults. Amazon EMR on Amazon EC2 and Amazon EMR Serverless use this optimized runtime, which is 1.5 times faster for read queries than EMR 7.0 based on an industry standard benchmark derived from TPC-DS at 3 TB scale and 3 times faster for write queries.

Apache Hive on Amazon EMR added over 10 features from Amazon EMR 7.0 to Amazon EMR 7.10 releases and continuing. These improvements are turned on by default and are 100% API compatible with Apache Hive. Some of the improvements include:

  • Default EMR enhanced S3A file system implementation for Apache Hive on Amazon EMR
  • Amazon EMR enhanced S3A zero-rename feature with 3-times improved write performance
  • Read query performance parity with EMR File System (EMRFS)
  • AWS Lake Formation support with Amazon EMR enhanced S3A
  • Fine-tuned file listing process for file formats including Parquet, Text, CSV, and so on
  • Async record reader initialization
  • Improvements to Tez task preemption
  • Fine-tuned locality during container reuse
  • Improved Tez relaxed locality
  • Improvements with split computation for ORC file formats

Transitioning from EMRFS to Amazon EMR enhanced S3A

The storage interface of Amazon EMR has evolved through two implementations: EMRFS and S3A. EMRFS, a proprietary Amazon Simple Storage Service (Amazon S3) connector developed by Amazon, has been the default filesystem for Amazon EMR since its early days, offering AWS-specific optimizations such as Consistent View for handling eventual consistency in Amazon S3, specialized performance tuning for the AWS environment, and seamless integration with AWS services through AWS Identity and Access Management (IAM) roles. On the other hand, S3A emerged from the Apache Hadoop open source community as a standard S3 connector and has evolved significantly through continuous improvements, performance optimizations, and enhanced S3 feature support. While EMRFS was designed specifically for optimal S3 access within Amazon EMR, S3A’s community-driven development has closed the performance gap with proprietary implementations.

Advantages of using enhanced S3A in Apache Hive on Amazon EMR

The transition from EMRFS to Amazon EMR enhanced S3A as the default filesystem in Amazon EMR 7.10 marks a strategic shift toward open source standardization while maintaining performance parity and adding benefits like improved portability and community support.

Based on the Amazon EMR HBase on Amazon S3 transitioning to EMR S3A with comparable EMRFS performance blog post, S3A in Amazon EMR Hive offers significant advantages over EMRFS, using modern AWS technologies and advanced storage capabilities.

  • The integration of AWS SDK v2 brings improved performance through non-blocking I/O, async clients, and better credential management.
  • S3A provides comprehensive support for Amazon S3 Glacier (Amazon S3 Glacier)and Amazon S3 Glacier Deep Archive, enabling cost-effective data lifecycle management and efficient handling of archival data for analytics.
  • It offers enhanced infrastructure flexibility with AWS Outposts support for on-premises deployments and custom endpoint support for Amazon S3-compatible storage systems, facilitating hybrid and multi-cloud architectures.
  • Performance is significantly boosted with Amazon S3 Express One Zone support, providing single-digit millisecond access for latency-sensitive analytics and interactive data exploration.
  • S3A introduces vector reads, allowing efficient access to columnar data formats by batching multiple non-contiguous byte ranges into a single S3 GET request, reducing I/O overhead and improving query performance.
  • The prefetching feature in S3A optimizes sequential read performance by proactively fetching data, enhancing throughput and reducing latency for large-scale data processing tasks.
  • S3A’s enhanced delegation token support, a result of AWS SDK v2 integration, provides flexible authentication mechanisms including support for web identity tokens and federated identity systems.

These advanced features make S3A a more versatile, efficient, and performance-oriented choice for organizations using Hive on Amazon EMR, particularly those requiring sophisticated data management and analytics capabilities across diverse infrastructure environments.

Read queries performance comparison

To evaluate the Amazon EMR Hive engine performance, we ran benchmark tests with the 3 TB TPC-DS datasets. We used Amazon EMR Hive clusters for benchmark tests on Amazon EMR and installed Apache Hive 3.1.3 on Amazon Elastic Compute Cloud (Amazon EC2) clusters designated for open source software (OSS) benchmark runs. We ran tests on separate EC2 clusters comprised of 16 m5.8xlarge instances for each of Apache Hive 3.1.3, Amazon EMR 7.0.0, Amazon EMR 7.5.0 and Amazon EMR 7.10.0. The primary node has 32 vCPU and 128 GB memory, and 16 worker nodes have a total of 512 vCPU and 2048 GB memory. We tested with Amazon EMR defaults to highlight the out-of-the-box experience and tuned Apache Hive with the minimal settings needed to provide a fair comparison.

For the source data, we chose the 3 TB scale factor, which contains 17.7 billion records, approximately 924 GB of compressed data in Parquet file format and ORC file format. The fact tables are partitioned by the date column, which consists of partitions ranging from 200–2,100. No statistics were pre-calculated for these tables. A total of 104 Hive SQL queries were run in five iterations sequentially and an average of each query’s runtime in these five iterations was used for comparison. The average of the five iterations’ runtime on Amazon EMR 7.10 was approximately 1.5 times faster than Amazon EMR 7.0. The following figure illustrates the total runtimes in seconds.

HiveReadPerformance1

The per-query speedup on Amazon EMR 7.10 when compared to Amazon EMR 7.0 is illustrated in the following chart. The horizontal axis represents queries in the TPC-DS 3 TB benchmark ordered by the Amazon EMR speedup descending and the vertical axis shows the speedup of queries due to the Amazon EMR runtime.

HivePerfQueries1

The below image illustrates the per-query speedup on Amazon EMR 7.10 when compared to Amazon EMR 7.0 for Parquet files.

HivePerfQueries2

Read cost comparison

Our benchmark outputs the total runtime and geometric mean figures to measure the Hive runtime performance by simulating a real-world complex decision support use case. The cost metric can provide us with additional insights. Cost estimates are computed using the following formulas. They factor in Amazon EC2, Amazon Elastic Block Store (Amazon EBS), and Amazon EMR costs, but don’t include Amazon S3 GET and PUT costs.

  • Amazon EC2 cost (including SSD cost) = number of instances * m5.8xlarge hourly rate * job runtime in hours
    • 8xlarge hourly rate = $1.536 per hour
  • Root Amazon EBS cost = number of instances * Amazon EBS per GB-hourly rate * root EBS volume size * job runtime in hours
  • Amazon EMR cost = number of instances * m5.8xlarge Amazon EMR cost * job runtime in hours
    • 8xlarge Amazon EMR cost = $0.27 per hour
  • Total cost = Amazon EC2 cost + root Amazon EBS cost + Amazon EMR cost

Based on the calculation, the Amazon EMR 7.10 benchmark result demonstrates a 33% improvement in job cost compared to Amazon EMR 7.0.

Metric Amazon EMR 7.0.0 Amazon EMR 7.10.0
Runtime in hours 2.86 < 2.00
Number of EC2 instances 17 17
Amazon EBS Size 20gb 20gb
Amazon EC2 cost $78.34 $52.22
Amazon EBS cost $0.01 $0.01
Amazon EMR cost $14.58 $9.72
Total cost $92.93 $61.96
Cost Savings Baseline Amazon EMR 7.10.0 is 33% better than Amazon EMR 7.0.0

Hive write committers performance comparison

Amazon EMR introduced a new committer to enhance Hive write performance on Amazon S3 up to 2.91 times faster. The existing Hive EMRFS S3-optimized committer, eliminates rename operations by writing data directly to the output location and only commits files at job completion to help enforce failure resilience. It implements a modified file naming convention that includes a query ID suffix. The new, Hive S3A-optimized committer, was developed to bring similar zero-rename capabilities to Hive on S3A, which previously lacked this feature. Built on OSS Hadoop’s Magic Committer, it eliminates unnecessary file movements during commit phases using S3 multipart upload (MPU) operations. This newer committer not only matches but exceeds EMRFS performance, delivering faster Hive write query execution while reducing S3 API calls, resulting in improved efficiency and cost savings for customers. Both committers effectively address the performance bottleneck caused by rename operations in Hive, with the S3A-optimized committer emerging as the superior solution.

Building on our previous blog post about the Amazon EMR Hive Zero Rename feature gains 15-fold write performance with EMRFS-optimized committer, we’ve achieved additional performance improvements in Hive write operations using the S3A optimized committer. We ran the comparison tests with and without the new committer and evaluated the write performance improvement. The benchmark used an insert overwrite query that joins two tables from a 3 TB TPC-DS ORC and Parquet dataset.

The following graph compares Hive write query total runtime speedup against ORC and Parquet formats. The y-axis denotes the speedup (total time taken with rename / total time taken by query with committer), and the x-axis denotes file formats and EMR deployment models. With the new S3A committer, the runtime speedup is better.

HiveWritePerf1

Understanding performance impact with different data sizes and number of files

To benchmark the performance impact with variable data sizes and number of files, we also evaluated the solution with various types, such as size of data (10 files –unpartitioned, 10 partitions, 100 partitions, 1000 partitions), number of files, and number of partitions: The results show that the number of files written is the critical factor for performance improvement when using this new committer in comparison to the default Hive commit logic and EMRFS committer.

In the following graph, the y-axis denotes the runtime speedup (total time taken with rename / total time taken by query with committer), and the x-axis denotes the number of partitions. We observed that as the number of partitions increases, the committer performs better because of avoiding multiple expensive rename operations in Amazon S3.

HiveWritePerf2

Write cost comparison

The following graph compares the number of overall Amazon S3 API calls for Hive write workflow against ORC and Parquet formats. The benchmark used an insert overwrite query that joins two tables from a 3 TB TPC-DS ORC, Parquet datasets on both Amazon EMR EC2 and Amazon EMR Serverless. With the new committer, the S3 usage cost is better(lower).

HiveWriteCost

Limitations with Hive S3A zero-rename feature

This committer will not be used, and default Hive commit logic will be applied in the following scenarios:

  • When merge small files (hive.merge.tezfiles) is enabled.
  • When using Hive ACID tables.
  • When partitions are distributed across file systems such as HDFS and Amazon S3.

Summary

Amazon EMR continues to improve the Amazon EMR runtime for Apache Hive, leading to a performance improvement year-over-year and additional features for big data customers to run their analytics workload in cost effective manner. More importantly, the transition to S3A brings additional benefits such as improved standardization, better portability, and stronger community support, while maintaining the robust performance levels established by EMRFS. We recommend that you stay up to date with the latest Amazon EMR release to take advantage of the latest performance and feature benefits.

To keep up to date, subscribe to the Big Data Blog RSS feed to learn more about Amazon EMR runtime for Apache Hive, configuration best practices, and tuning advice.


About the authors

Himanshu Mishra

Himanshu Mishra

Himanshu is a Senior software development engineer for Amazon EMR at Amazon Web Services. His expertise is in Amazon EMR and Hive Query engine. He is passionate about distributed systems and helping people to bring their ideas to life.

Anmol Sundaram

Anmol Sundaram

Anmol is a Software development engineer for Amazon EMR at Amazon Web Services. His expertise is in Amazon EMR and Hive Query engine. His dedication to solving distributed problems is helping Amazon EMR to achieve higher performance improvements.

Paramvir Singh

Paramvir Singh

Paramvir is a Software development engineer for Amazon EMR at Amazon Web Services. His expertise in Amazon EMR and Hive Query engine helped the team achieve performance improvements.

Ramesh Kandasamy

Ramesh Kandasamy

Ramesh is an Engineering Manager for Amazon EMR at Amazon Web Services. He is a long tenured Amazonian dedicated to solving distributed systems problems.

author name

Giovanni Matteo Fumarola

Giovanni is the Senior Manager for the Amazon EMR Spark and Iceberg group. He is an Apache Hadoop Committer and PMC member. He has been focusing on the big data analytics space since 2013.

How Socure achieved 50% cost reduction by migrating from self-managed Spark to Amazon EMR Serverless

Post Syndicated from Junaid Effendi, Pengyu Wang original https://aws.amazon.com/blogs/big-data/how-socure-achieved-50-cost-reduction-by-migrating-from-self-managed-spark-to-amazon-emr-serverless/

Socure is one of the leading providers of digital identity verification and fraud solutions. Its predictive analytics platform applies artificial intelligence (AI) and machine learning (ML) techniques to process both online and offline intelligence, including government-issued documents, contact information (email, phone, address), personal identifiers (DOB, SSN), and device or network data (IP, velocity) to verify identities accurately and in real time.

Socure ID+ is an identity verification platform that uses multiple Socure offerings such as KYC, SIGMA, eCBSV. Phone Risk and more. It has two environments focused on proof of concept (POC) and live customers. The Data Science (DS) environment is designed for the POC or proof of value (POV) stage. In this environment, customers provide datasets via SFTP, which are processed by Socure’s data scientists through an internal endpoint. The data undergoes ML-based scoring and other intelligence calculations depending on the selected modules and processed results are stored in Amazon Simple Storage Service (Amazon S3) in delta open table format . In the Production (Prod) environment, customers can verify identities either in real time through live endpoints or via a batch processing interface.

Socure’s data science environment includes a streaming pipeline called Transaction ETL (TETL), built on OSS Apache Spark running on Amazon EKS. TETL ingests and processes data volumes ranging from small to large datasets while maintaining high-throughput performance.

The primary purpose of this pipeline is to give data scientists a flexible environment to run POC workloads for customers.

Data scientists…

  • trigger ingestion of POC datasets, ranging from small batches to large-scale volumes.
  • consume the processed outputs written by the pipeline for analysis and model development.
  • share the results with Socure’s customers.

The following diagram shows the Transaction ETL (TETL) architecture.

Transaction ETL architecture

This pipeline directly supports customer POCs, ensuring that the right data is available for experimentation, validation, and demonstration. As such, it is a critical link between raw data and customer-facing outcomes, making its reliability and performance essential for delivering value. In this post, we show how Socure was able to achieve 50% cost reduction by migrating the TETL streaming pipeline from self-managed spark to Amazon EMR serverless.

Motivation

As data volumes have scaled by 10x, several challenges like latency and data reliability have emerged that directly impact the customer experience:

  • Performance issues due to inefficient autoscaling leading to increase in latency up to 5x
  • High operational cost of maintaining an OSS Spark environment on EKS

Additionally, we have identified other important issues:

  • Resource constraints due to instance provisioning limits, forcing the use of smaller nodes. This leads to frequent spark executor out of memory (OOM) failures under heavy loads, increasing job latency and delaying data availability.
  • Performance bottlenecks with Delta Lake, where large batch operations such as OPTIMIZE compete for resources and slow down streaming workloads.

During this migration, we also took the opportunity to transition to AWS Graviton, enabling additional cost efficiencies as explained in this post.

With these two primary drivers we began exploring alternative architecture using Amazon EMR. We already dd extensive benchmarking on several identity verification related batch workloads on different EMR platforms and came to the conclusion that Amazon EMR Serverless (EMR-S) offers a path to reduce operational cost, improve reliability, and better handle large-scale batch and streaming workloads; tackling both customer-facing issues and platform-level inefficiencies.

The new pipeline architecture

The data processing pipeline follows a two-stage architecture where streaming data from Amazon Kinesis Data Stream first flows into the raw layer, which parses incoming data into large JSON blobs, applies encryption, and stores the results in append-only Delta Tables. The processed layer consumes data from these raw Delta tables, performs decryption, transforms the data into a flattened and wide structure with proper field parsing, applies individual encryption to personally identifiable information (PII) fields, and writes the refined data to separate append-only Delta Tables for downstream consumption.

The following diagram shows the TETL before/after architecture we implemented, transitioning from OSS Spark on EKS to Spark on EMR Serverless.

Transaction ETL architecture

Benchmarking

We benchmarked end-to-end pipeline performance across OSS Spark on EKS and EMR Serverless. The evaluation focused on latency and cost under comparable resource configurations.

Resource Configuration

EKS (OSS Spark):

  • Min 30 executors
  • Max 90 executors
  • 14 GB memory / 2 cores per executor

EMR Serverless:

  • Min 10 executors
  • Max 30 executors
  • 27 GB memory / 4 cores per executor
  • Effectively ~60 executors when normalized for 2x memory and cores, designed to mitigate the OOM issues described earlier.

Observations

  • Autoscaling Efficiency: EMR Serverless scaled down effectively to 20 workers on average over the weekend (low traffic day), resulting in lower costs up to 12% compared to weekday.
  • Executor Sizing: Larger executors on EMR Serverless prevented OOM failures and improved stability under load.

Definitions

  • Cost: It is the service cost for both raw & processed jobs from the AWS Cost Explorer.
  • Latency: End-to-end latency measures the time from Socure ID+ event generation until data arrives in the processed delta table, calculated as Inserted Date minus Event Date.

Results

The values in the following table represent percentage improvements observed when running on EMR compared to EKS.

Low Traffic (Weekend) Regular Traffic (Weekday)
Records Count ~1M ~5M
Min Latency (best case) 73.3% 69.2%
Avg Latency (representative workload) 51.0% 47.9%

Max Latency

(worst case)

12.3% 34.7%
Total Cost 57.1% 45.2%

Note: Even with a conservative 40% cost reduction applied to the EKS environment to account for Graviton, EMR-S remains approximately 15% cheaper.

Performance improvement graph

The benchmarking results clearly demonstrate that EMR Serverless outperforms OSS Spark on EKS for our end-to-end pipeline workloads. By moving to EMR Serverless, we achieved:

  • Improved performance: Average latency reduced by more than 50%, with consistently lower min and max latencies.
  • Cost efficiency: Overall pipeline execution costs dropped by more than half.
  • Scalability: Autoscaling optimized resource usage, further lowering cost during off-peak periods.
  • Operational overhead: EMR-S fully managed and serverless nature eliminates the need to maintain EKS and OSS Spark.

Conclusion

In this post, we showed how Socure transitioning to EMR Serverless not only resolved critical issues around cost, reliability, and latency, but also provided a more scalable and sustainable architecture for serving customer POCs effectively, enabling us to deliver results to customers faster and strengthen our position for potential custom contracts.


About the authors

Junaid Effendi

Junaid Effendi

Junaid is a Senior Data Engineer at Socure. He designs and builds data infrastructure, pipelines, and services for both batch and streaming workloads, enabling data-driven insights that power identity verification. In his free time, he enjoys writing tech blogs and playing soccer.

Pengyu Wang

Pengyu Wang

Pengyu is a Senior Manager of Data Engineering at Socure. He leads teams that design and build scalable data platforms and pipelines, driving high-quality data solutions that power identity verification and analytics. In his free time, he enjoys skiing in the winter and exploring new technologies.

Raj Ramasubbu

Raj Ramasubbu

Raj is a Senior Analytics Specialist Solutions Architect focused on big data and analytics and AI/ML with Amazon Web Services. He helps customers architect and build highly scalable, performant, and secure cloud-based solutions on AWS. Raj provided technical expertise and leadership in building data engineering, big data analytics, business intelligence, and data science solutions prior to joining AWS. He helped customers in various industries like healthcare, medical devices, life science, retail, asset management, car insurance, residential REIT, agriculture, title insurance, supply chain, document management, and real estate.

Implementing HTTP Strict Transport Security (HSTS) across AWS services

Post Syndicated from Abhishek Avinash Agawane original https://aws.amazon.com/blogs/security/implementing-http-strict-transport-security-hsts-across-aws-services/

Modern web applications built on Amazon Web Services (AWS) often span multiple services to deliver scalable, performant solutions. However, customers encounter challenges when implementing a cohesive HTTP Strict Transport Security (HSTS) strategy across these distributed architectures.

Customers face fragmented security implementation challenges because different AWS services require distinct approaches to HSTS configuration, leading to inconsistent security postures.Applications using Amazon API Gateway for APIs, Amazon CloudFront for content delivery, and Application load balancers for web traffic lack unified HSTS policies, leading to complex multi-service environments. Security scanners flag missing HSTS headers, but remediation guidance is scattered across service-specific documentation, causing security compliance gaps.

HSTS is a web security policy mechanism that protects websites against protocol downgrade attacks and cookie hijacking. When properly implemented, HSTS instructs browsers to interact with applications exclusively through HTTPS connections, providing critical protection against man-in-the-middle issues.

This post provides a comprehensive approach to implementing HSTS across key AWS services that form the foundation of modern cloud applications:

  1. Amazon API Gateway: Secure REST and HTTP APIs with centralized header management
  2. Application Load Balancer: Infrastructure-level HSTS enforcement for web applications
  3. Amazon CloudFront: Edge-based security header delivery for global content

By following the implementation steps in this post, you can establish a unified HSTS strategy that aligns with AWS Well-Architected Framework security principles while maintaining optimal application performance.

Understanding HSTS security and its benefits

HTTP Strict Transport Security is a web security policy mechanism that helps protect websites against protocol downgrade attacks and cookie hijacking. When a web server declares HSTS policy through the Strict-Transport-Security header, compliant browsers automatically convert HTTP requests to HTTPS for the specified domain. This enforcement occurs at the browser level, providing protection even before the initial request reaches your infrastructure.

HSTS enforcement applies specifically to web browser clients. Most programmatic clients (such as SDKs, command line tools, or application-to-application communication) don’t enforce HSTS policies. For comprehensive security, configure your applications and infrastructure to only use HTTPS connections regardless of client type rather than relying solely on HSTS for protocol enforcement.

HTTP to HTTPS redirection enforcement on the server ensures future requests reach your applications over encrypted connections. However, it leaves a security gap during the initial browser request. Understanding this gap helps explain why client-side HSTS serves as an essential security layer in modern web applications.

For example, when users access web applications, the typical flow with redirects configured is as follows:

  1. User enters example.com in their browser.
  2. Browser sends an HTTP request to http://example.com.
  3. Server responds with HTTP 301/302 redirect to https://example.com.
  4. Browser follows redirection and establishes HTTPS connection

The initial HTTP request in step 2 creates an opportunity for protocol downgrade issues. An unauthorized party positioned between the user and your infrastructure can intercept this request and respond with content that appears legitimate while maintaining an insecure connection. This technique, known as SSL stripping, can occur even when your server-side AWS infrastructure is properly configured with HTTPS redirects.

HSTS addresses this security gap by moving security enforcement to the browser level. After a browser receives an HSTS policy, it automatically converts HTTP requests to HTTPS before sending them over the network:

  1. User enters example.com in browser.
  2. Browser automatically converts to HTTPS due to stored HSTS policy.
  3. Browser sends HTTPS request directly to https://example.com.
  4. No initial HTTP request removes the opportunity for interception.

This browser-level enforcement provides protection that complements your AWS infrastructure security configurations, creating defense in depth against protocol downgrade issues.

Although current browsers warn about insecure connections, HSTS provides programmatic enforcement. This prevents unauthorized parties from exploiting the security gap because they can’t forge valid HTTPS certificates for protected domains.

The security benefits of HSTS extend beyond simple protocol enforcement. HSTS helps prevent protocol downgrade issues after HSTS policy is established in the browser. It mitigates against man-in-the-middle issues, preventing unauthorized parties from intercepting communications. It also helps prevent unauthorized session access to protect against credential theft and unintended session access.
HSTS requires HTTPS connections and removes the option to bypass certificate warnings.

This post focuses exclusively on implementing the HTTP Strict-Transport-Security header. Although the examples include additional security headers for completeness, detailed configuration of those headers is beyond the scope of this post.

Key use cases for HSTS implementation

HSTS protects scenarios that HTTP redirects miss. For example, when legacy systems serve mixed content, or when SSO flows redirect users between providers, HSTS keeps connections encrypted throughout.

Applications serving both modern HTTPS content and legacy HTTP resources face protocol downgrade risks. When users access example.com/app that loads resources from legacy.example.com, HSTS prevents browsers from making initial HTTP requests to any subdomain, eliminating the vulnerability window during resource loading.

SSO implementations redirecting users between identity providers and applications create multiple HTTP request opportunities. Due to HSTS, authentication tokens and session data remain encrypted throughout the entire SSO flow, preventing credential interception during provider redirects.

Microservices architectures using API Gateway often involve service-to-service communication and client redirects. HSTS protects API endpoints from protocol downgrade during initial client connections, which means that API keys and authentication headers are not transmitted over HTTP.

Applications using CloudFront with multiple origin servers face security challenges when origins change or fail over. HSTS prevents browsers from falling back to HTTP when accessing cached content or during origin failover scenarios, maintaining encryption even during infrastructure changes.

From an AWS Well-Architected perspective, implementing HSTS demonstrates adherence to the defense in depth principle by adding an additional layer of security at the application protocol level. This approach complements other AWS security services and features, creating a comprehensive security posture that helps to protect data both in transit and at rest.

Implementing HSTS with Amazon API Gateway

Amazon API Gateway lacks built-in features to enable HSTS for the API resources. There are several different ways to configure HSTS headers in HTTP APIs and REST APIs.
For HTTP APIs, you can configure response parameter mapping to set HSTS headers when it’s invoked using a default endpoint or custom domain.

To configure response parameter mapping:

  1. Navigate to your desired HTTP API’s route configuration in the AWS API Gateway console
  2. Access the route’s integration settings under Manage integrations tab.
Figure 1: Integration settings of the HTTP Api

Figure 1: Integration settings of the HTTP Api

  1. To configure parameter mapping, under Response key, enter 200.
  2. Under Modification type, select Append in the dropdown menu.
  3. Under “Parameter to modify”, enter header.Strict-Transport-Security
  4. Under Value, enter max-age=31536000; includeSubDomains; preload.
Figure 2: Parameter Mapping for the HTTP Api integration

Figure 2: Parameter Mapping for the HTTP Api integration

REST APIs in Amazon API Gateway offer more granular control over HSTS implementation through both proxy and non-proxy integration patterns.

For proxy integrations, the backend service assumes responsibility for HSTS header generation. For example, an AWS Lambda proxy integration must return the HSTS headers in its response as shown in the following code example:

import json 
def lambda_handler(event, context):     
	return {         
        'statusCode': 200,         
        'headers': {             
            'Strict-Transport-Security': 'max-age=31536000; includeSubDomains; preload'         
        },         
        'body': json.dumps('Secure response with HSTS headers')     
    }

For non-proxy integrations, the HSTS headers must be returned by the Rest API by implementing one of two methods, either mapping templates or method response.

In the mapping templates method, the mapping template is used to configure the HSTS headers. The Velocity Template Language (VTL) for the mapping template is used for dynamic header generation. To implement this method:

  1. Navigate to the desired REST API and click on the method for the desired resource.
  2. Under the ‘Integration response’ tab, use the following mapping template to set the response headers:
$input.json("$") 
#set($newValue = "$input.params().header.get('Host')") 
#set($context.responseOverride.header.Strict-Transport-Security 
= "max-age=31536000; includeSubDomains; preload")

Figure 3: Adding mapping template to integration response of the Rest Api

Figure 3: Adding mapping template to integration response of the Rest Api

The ‘Method response’ tab provides declarative configuration through explicit header mapping in the configuration. To implement this method:

  1. Navigate to your desired REST API and select the method for the desired resource.
  2. Choose Method response and under Header name, add the HSTS header strict-transport-security.
Figure 4: Method response of the Rest Api

Figure 4: Method response of the Rest Api

3. Choose Integration response and under Header mappings, enter the HSTS header strict-transport-security. Add the Mapping value for the header as max-age=31536000; includeSubDomains; preload.

Figure 5: Integration response of the Rest Api

Figure 5: Integration response of the Rest Api

To test and validate, use the following command:

Verify HSTS implementation for both HTTP API and REST API using curl with response headers logged:

curl -i https://your-api-gateway-url.execute-
api.region.amazonaws.com/stage/resource

The expected response should include:

HTTP/2 200 

date: Tue, 20 Sep 2025 16:34:35 GMT 
content-type: application/json 
content-length: 3 
x-amzn-requestid: 76543210-9aaa-4bbb-accc-987654321012
strict-transport-security: max-age=31536000; includeSubDomains; preload 
x-amz-apigw-id: ABCDEFGHIJKLMNO

Implementing HSTS with AWS Application Load Balancers

Application Load Balancers now provide built-in support for HTTP response header modification, including HSTS headers. This lets you enforce consistent security policies across all your services from a single point, reducing development effort and ensuring uniform protection regardless of which backend technologies you’re using.

Prerequisites and infrastructure requirements

Before implementing HSTS with load balancers, ensure your infrastructure meets these requirements:

  • Functional HTTPS listener – The ALB listener must be configured with HTTPS correctly.
  • Valid certificates – The ALB listener must have proper TLS certificate chain in AWS Certificate Manager and validation.
  • Application Load Balancer – The header modification feature for the ALB must be enabled for the listener since it is turned off by default.

Configuration

Application Load Balancers support direct HSTS header injection through the response header modification feature. This approach provides centralized security policy enforcement without requiring individual application configuration.

To enable HTTP header modification for your Application Load Balancer:

  1. Open the Amazon Elastic Compute Cloud (Amazon EC2) console and navigate to Load Balancers.
  2. Select your Application Load Balancer.
  3. On the Listeners and rules tab, select the HTTPS listener.
  4. On the Attributes tab, choose Edit.
    Figure 6: ALB HTTPS listener Attributes configuration

    Figure 6: ALB HTTPS listener Attributes configuration

  5. Expand the Add response headers section.
  6. Select Add HTTP Strict Transport Security (HSTS) header.
  7. To configure the header value, enter max-age=31536000; includeSubDomains; preload.
  8. Choose Save changes.
Figure 7: Add response headers in attributes configuration of the ALB HTTPS listener

Figure 7: Add response headers in attributes configuration of the ALB HTTPS listener

Header modification behavior

When ALB header modification is enabled:

  • Header addition – If the backend response doesn’t include the specified header, ALB adds it with the configured value
  • Header override – If the backend response includes the header, ALB replaces the existing value with the configured value
  • Centralized control – Responses from the load balancer include the configured security headers, ensuring consistent policy enforcement

To test and validate, use the following command:
curl -I https://my-loadbalancer-1234567890.us-west-2.elb.amazonaws.com

The following code example shows the expected response headers:

HTTP/2 200
date: Tue, 23 Sep 2025 16:34:35 GMT
strict-transport-security: max-age=31536000; includeSubDomains; preload

Header value constraints:

  • Maximum header value size – 1 KB
  • Supported characters – Alphanumeric (a-z, A-Z, 0-9) and special characters (_ :;.,/’?!(){}[]@<>=-+*#&`|~^%)
  • Empty values revert to default behavior (no header modification)

When implementing header modifications, there are several operational considerations to keep in mind. Header modification must be explicitly enabled on each listener where you want the functionality to work. Once enabled, any changes you configure will apply to all responses that come from the load balancer, affecting every request processed through that listener. Application Load Balancer performs basic input validation on the headers you configure, but it has limited capability for header-specific validation, so you should ensure your header configurations follow proper formatting and standards.

This built-in Application Load Balancer capability significantly simplifies HSTS implementation by eliminating the need for backend application modifications while providing centralized security policy enforcement across your entire application infrastructure.

Implementing HSTS with Amazon CloudFront

Amazon CloudFront provides built-in support for HTTP security headers, including HSTS, through response headers policies. This feature enables centralized security header management at the CDN edge, providing consistent policy enforcement across cached and non-cached content.

Response headers policy configuration

You can use the CloudFront response headers policy feature to configure security headers that are automatically added to responses served by your distribution. You can use managed response headers policies that include predefined values for the most common HTTP security headers. Or, you can create a custom response header policy with custom security headers and values that you can add to the required CloudFront behavior.

To configure security headers:

  1. On the CloudFront console, navigate to Policies and then Response headers.
  2. Choose Create response headers policy.
  3. Configure policy settings:
    • Name – HSTS-Security-Policy
    • Description – HSTS and security headers for web applications
  4. Under Security headers, configure:
    • Strict Transport Security – Select
    • Max age – 31,536,000 seconds (1 year)
    • Preload – Select (optional)
    • IncludeSubDomains – Select (optional)
  5. Add additional security headers:

    • X-Content-Type-Options
    • X-Frame-Options – Select Origin as “SAMEORIGIN”
    • Referrer-Policy – Select “strict-origin-when-cross-origin”
    • X-XSS-Protection – Select “Enabled”, Tick “Block”
    • Choose Create.
Figure 8: Configuring response header policy for the Cloudfront distribution

Figure 8: Configuring response header policy for the Cloudfront distribution

To attach the policy to the distribution:

  1. Navigate to your CloudFront distribution.
  2. Select the Behaviors tab.
  3. Edit the default behavior (or create a new one).
  4. Under Response headers policy, select your created policy.
  5. Choose Save changes.
Figure 9: Selecting the response headers policy

Figure 9: Selecting the response headers policy

Header override behavior:
CloudFront response headers policies provide origin override functionality that controls how headers are managed between the origin and CloudFront. When origin override is enabled, CloudFront will replace existing headers that come from the origin server. Conversely, when origin override is disabled, CloudFront will only add the policy-defined headers if those same headers are not already present in the origin response, preserving the original headers from the source.

To test and validate, use the following command:

curl -I https://your-cloudfront-domain.cloudfront.net

The following code example shows the expected response headers:

HTTP/2 200 
date: Tue, 23 Sep 2025 16:34:35 GMT 
strict-transport-security: max-age=31536000; includeSubDomains; preload 
x-content-type-options: nosniff 
x-frame-options: SAMEORIGIN 
referrer-policy: strict-origin-when-cross-origin 
x-xss-protection: 1; mode=block 
x-cache: Hit from cloudfront

Using CloudFront has several advantages. It offers consistent header application across all content types and centralized security policy management. Edge-level enforcement reduces latency, and no origin server modifications are required. AWS edge locations offer global policy distribution.

Security considerations and best practices

Implementing HSTS requires careful consideration of several security implications and operational requirements.

The max-age directive determines how long browsers will enforce HTTPS-only access. The duration guidelines are as follows:

  • 300 seconds (5 minutes) – Safe for experimentation during initial testing phase.
  • 86,400 seconds (1 day) – For short-term commitment such as development environments.
  • 259,2000 seconds (30 days) – For medium-term validation such as staging environments.
  • 31,536,000 seconds (1 year) – For long-term commitment such as production environments.

We recommend that you start with shorter max-age values during initial implementation and gradually increase them as you gain confidence in your HTTPS infrastructure stability.

The includeSubDomains directive extends HSTS enforcement to all subdomains. It offers several benefits, including comprehensive protection across the entire domain hierarchy, prevention of subdomain-based attacks, and simplified security policy management.

Requirements for using this directive include:

  • Subdomains should support HTTPS to use this directive effectively.
  • Subdomains should have valid SSL certificates.
  • You must maintain a consistent security policy across domain hierarchy.

Consider implementing HSTS preloading for maximum security coverage:

Strict-Transport-Security: max-age=31536000; includeSubDomains; preload

Preloading benefits include protection for first-time visitors, browser-level enforcement before network requests, and maximizing security coverage.

The following are some preloading considerations:

  • It requires submission to browser preload lists.
  • It’s difficult to reverse because removal takes months.
  • It requires long-term commitment to HTTPS infrastructure.

For more information, see:

Conclusion

Implementing HSTS across AWS services provides a robust foundation for securing web applications against protocol downgrade attacks and enabling encrypted communications. By using the built-in capabilities of API Gateway, CloudFront, and Application Load Balancers, organizations can create comprehensive security policies that align with AWS Well-Architected Framework principles.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Abhishek Avinash Agawane

Abhishek is a Security Consultant at Amazon Web Services with more than 8 years of industry experience. He helps organizations architect resilient, secure, and efficient cloud environments, guiding them through complex challenges and large-scale infrastructure transformations. He has helped numerous organizations enhance their cloud operations through targeted optimizations, robust architectures, and best-practice implementations.

Introducing AWS Glue 5.1 for Apache Spark

Post Syndicated from Chiho Sugimoto original https://aws.amazon.com/blogs/big-data/introducing-aws-glue-5-1-for-apache-spark/

AWS Glue is a serverless, scalable data integration service that makes it simple to discover, prepare, move, and integrate data from multiple sources. AWS recently announced Glue 5.1, a new version of AWS Glue that accelerates data integration workloads in AWS. AWS Glue 5.1 upgrades the Spark engines to Apache Spark 3.5.6, giving you newer Spark release along with the newer dependent libraries so you can develop, run, and scale your data integration workloads and get insights faster.

In this post, we describe what’s new in AWS Glue 5.1, key highlights on Spark and related libraries, and how to get started on AWS Glue 5.1.

What’s new in AWS Glue 5.1

The following updates are in AWS Glue 5.1:

Runtime and library upgrades

AWS Glue 5.1 upgrades the runtime to Spark 3.5.6, Python 3.11, and Scala 2.12.18 with new improvements from the open source version. AWS Glue 5.1 also updates support for open table format libraries to Apache Hudi 1.0.2, Apache Iceberg 1.10.0, and Delta Lake 3.3.2 so you can solve advanced use cases around performance, cost, governance, and privacy in your data lakes.

Support for new Apache Iceberg features

AWS Glue 5.1 adds support for Apache Iceberg Materialized View, and Apache Iceberg format version 3.0. AWS Glue 5.1 also adds support for data writes into Iceberg and Hive tables with Spark-native fine-grained access control with AWS Lake Formation.

Apache Iceberg Materialized View is especially useful in cases where you need to accelerate frequently run queries on large data sets by pre-computing expensive aggregations. If you would like to learn more about Apache Iceberg materialized views, refer to Introducing Apache Iceberg materialized views in AWS Glue Data Catalog.

Apache Iceberg format version 3.0 is the latest Iceberg format version defined in Iceberg Table Spec. Following features are supported:

Create an Iceberg V3 format table

To create an Iceberg V3 format table, specify the format-version to 3 when creating the table. The following is a sample PySpark script: (replace amzn-s3-demo-bucket with your S3 bucket name):

from pyspark.sql import SparkSession

s3bucket = "amzn-s3-demo-bucket" 
database = "glue51_blog_demo" 
table_name = "iceberg_v3_table_demo"

spark = (
    SparkSession.builder
    .config("spark.sql.extensions", "org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions")
    .config("spark.sql.defaultCatalog", "glue_catalog")
    .config("spark.sql.catalog.glue_catalog", "org.apache.iceberg.spark.SparkCatalog")
    .config("spark.sql.catalog.glue_catalog.type", "glue")
    .config("spark.sql.catalog.glue_catalog.warehouse", f"s3://{s3bucket}/{database}/{table_name}/")
    .getOrCreate()
)

spark.sql(f"CREATE DATABASE IF NOT EXISTS {database}")

# Create Iceberg table with V3 format-version
spark.sql(f"""
    CREATE TABLE IF NOT EXISTS {database}.{table_name} (
        id int,
        name string,
        age int,
        created_at timestamp
    ) USING iceberg
    TBLPROPERTIES (
        'format-version'='3',
        'write.delete.mode'='merge-on-read'
    )
""")

To migrate from V2 format to V3, use ALTER TABLE ... SET TBLPROPERTIES to update the format-version. The following is a sample PySpark script:

spark.sql(f"ALTER TABLE {database}.{table_name} SET TBLPROPERTIES ('format-version'='3')")

You cannot rollback from V3 to V2, so you need to be careful to verify that all your Iceberg clients support Iceberg V3 format version. Once upgraded, older versions cannot correctly read newer format versions, as Iceberg table format versions are not forward-compatible.

Create a table with Row Lineage tracking enabled

To create a table with Row Lineage tracking enabled, set the table property row-lineage to true. The following is a sample PySpark script:

# Create Iceberg table with row-lineage-tracking
spark.sql(f"""
    CREATE TABLE IF NOT EXISTS {database}.{table_name} (
        id int,
        name string,
        age int,
        created_at timestamp
    ) USING iceberg
    TBLPROPERTIES (
        'format-version'='3',
        'row-lineage'='true',
        'write.delete.mode'='merge-on-read'
    )
""")

In tables with Row Lineage tracking enabled, row IDs are managed at the metadata level for tracking row modifications over time and auditing.

Extended support for AWS Lake Formation permissions

Fine-grained access control with Lake Formation has been supported through native Spark DataFrames and Spark SQL in Glue 5.0 for read operations. Glue 5.1 extends fine-grained access control for write operations.

Full-Table Access (FTA) control in Apache Spark were introduced for Apache Hive and Iceberg tables in Glue 5.0. Glue 5.1 extends FTA support for Apache Hudi tables and Delta Lake tables.

S3A by default

AWS Glue 5.1 uses S3A as the default S3 connector. This change aligns with the recent Amazon EMR adoption of S3A as the default connector and brings enhanced performance and advanced features to Glue workloads. For more details about the S3A connector’s capabilities and optimizations, see Optimize Amazon EMR runtime for Apache Spark with EMR S3A.

Note when migrating from Glue 5.0 to Glue 5.1, If both spark.hadoop.fs.s3a.endpoint and spark.hadoop.fs.s3a.endpoint.region are not set, the default region used by S3A is us-east-2. This may cause issues. To mitigate the issues caused by this change, set the spark.hadoop.fs.s3a.endpoint.region Spark configuration when using the S3A file system in AWS Glue 5.1.

Dependent library upgrades

AWS Glue 5.1 upgrades the runtime to Spark 3.5.6, Python 3.11, and Scala 2.12.18 with upgraded dependent libraries.

The following table lists dependency upgrades:

Dependency Version in AWS Glue 5.0 Version in AWS Glue 5.1
Spark 3.5.4 3.5.6
Hadoop 3.4.1 3.4.1
Scala 2.12.18 2.12.18
Hive 2.3.9 2.3.9
EMRFS 2.69.0 2.73.0
Arrow 12.0.1 12.0.1
Iceberg 1.7.1 1.10.0
Hudi 0.15.0 1.0.2
Delta Lake 3.3.0 3.3.2
Java 17 17
Python 3.11 3.11.14
boto3 1.34.131 1.40.61
AWS SDK for Java 2.29.52 2.35.5
AWS Glue Data Catalog Client 4.5.0 4.9.0
EMR DynamoDB Connector 5.6.0 5.7.0

The following are database connector (JDBC driver) upgrades:

Driver Connector version in AWS Glue 5.0 Connector version in AWS Glue 5.1
MySQL 8.0.33 8.0.33
Microsoft SQL Server 10.2.0 10.2.0
Oracle Databases 23.3.0.23.09 23.3.0.23.09
PostgreSQL 42.7.3 42.7.3
Amazon Redshift redshift-jdbc42-2.1.0.29 redshift-jdbc42-2.1.0.29

The following are Spark connector upgrades:

Driver Connector version in AWS Glue 5.0 Connector version in AWS Glue 5.1
Amazon Redshift 6.4.0 6.4.2
OpenSearch 1.2.0 1.2.0
MongoDB 10.3.0 10.3.0
Snowflake 3.0.0 3.1.1
BigQuery 0.32.2 0.32.2
AzureCosmos 4.33.0 4.33.0
AzureSQL 1.3.0 1.3.0
Vertica 3.3.5 3.3.5

Get started with AWS Glue 5.1

You can start using AWS Glue 5.1 through AWS Glue Studio, the AWS Glue console, the latest AWS SDK, and the AWS Command Line Interface (AWS CLI).

To start using AWS Glue 5.1 jobs in AWS Glue Studio, open the AWS Glue job and on the Job Details tab, choose the version Glue 5.1 – Supports Spark 3.5, Scala 2, Python 3.

To start using AWS Glue 5.1 on an AWS Glue Studio notebook or an interactive session through a Jupyter notebook, set 5.1 in the %glue_version magic:

%%glue_version 5.1

The following output shows that the session is set to use AWS Glue 5.1:

Setting Glue version to: 5.1

Spark Troubleshooting with Glue 5.1

To accelerate Apache Spark troubleshooting and job performance optimization for your Glue 5.1 ETL jobs, you can use the newly introduced Apache Spark troubleshooting agent. Traditional Spark troubleshooting requires extensive manual analysis of logs, performance metrics, and error patterns to identify root causes and optimization opportunities. The agent simplifies this process through natural language prompts, automated workload analysis, and intelligent code recommendations. The agent has three main components: an MCP-compatible AI assistant in your development environment for interaction, the MCP proxy for AWS that handles secure communication between your client and the MCP server, and an Amazon SageMaker Unified Studio managed MCP Server (preview) that provides specialized Spark troubleshooting and upgrade tools for Glue 5.1 jobs.

To set up the agent, follow the instructions to set up the resources and MCP configuration: Setup for Apache Spark Troubleshooting agent. Then, you can launch your preferred MCP client and use conversation to interact with the tools for troubleshooting.

The following is a demonstration on how you can use the Apache Spark troubleshooting agent with Kiro CLI to debug a Glue 5.1 job run.

For more information and video walkthroughs for how to use the Apache Spark troubleshooting agent, please refer to Apache Spark Troubleshooting agent for Amazon EMR.

Conclusion

In this post, we discussed the key features and benefits of AWS Glue 5.1. You can create new AWS Glue jobs on AWS Glue 5.1 or migrate your existing AWS Glue jobs to benefit from the improvements.

We would like to thank the support of numerous engineers and leaders who helped build Glue 5.1 to support customers with a performance optimized Spark runtime and deliver new capabilities.


About the authors

Chiho Sugimoto

Chiho is a Cloud Support Engineer on the AWS Big Data Support team. She is passionate about helping customers build data lakes using ETL workloads. She loves planetary science and enjoys studying the asteroid Ryugu on weekends.

Noritaka Sekiyama

Noritaka is a Principal Big Data Architect at the AWS Analytics product team. He’s responsible for designing new features in AWS products, building software artifacts, and providing architecture guidance to customers. In his spare time, he enjoys cycling on his road bike.

Peter Tsai

Peter is a Software Development Engineer at AWS, where he enjoys solving challenges in the design and performance of the AWS Glue runtime. In his leisure time, he enjoys hiking and cycling.

Bo Li

Bo Li is a Senior Software Development Engineer on the AWS Glue team. He is devoted to designing and building end-to-end solutions to address customers’ data analytic and processing needs with cloud-based, data-intensive and GenAI technologies.

Kartik Panjabi

Kartik is a Software Development Manager on the AWS Glue team. His team builds generative AI features for the Data Integration and distributed system for data integration.

Peter Manastyrny

Peter is a Product Manager focusing on data processing and data integration workloads at AWS. He is working on making AWS Glue the best tool for building and operating complex integrated data pipelines.

Achieve 2x faster data lake query performance with Apache Iceberg on Amazon Redshift

Post Syndicated from Kalaiselvi Kamaraj original https://aws.amazon.com/blogs/big-data/achieve-2x-faster-data-lake-query-performance-with-apache-iceberg-on-amazon-redshift/

With the growing adoption of open table formats like Apache Iceberg, Amazon Redshift continues to advance its capabilities for open format data lakes. In 2025, Amazon Redshift delivered several performance optimizations that improved query performance over twofold for Iceberg workloads on Amazon Redshift Serverless, delivering exceptional performance and cost-effectiveness for your data lake workloads.

In this post, we describe some of the optimizations that led to these performance gains. Data lakes have become a foundation of modern analytics, helping organizations store vast amounts of structured and semi-structured data in cost-effective data formats like Apache Parquet while maintaining flexibility through open table formats. This architecture creates unique performance optimization opportunities across the entire query processing pipeline.

Performance enhancements

Our latest enhancements span multiple areas of the Amazon Redshift SQL query processing engine, including vectorized scanners that accelerate execution, optimal query plans powered by just-in-time (JIT) runtime statistics, distributed Bloom filters, and new decorrelation rules.

The following chart summarizes the performance improvements achieved so far in 2025, as measured by industry standard 10 TB TPC-DS and TPC-H benchmarks run on Iceberg tables on an 88 RPU Redshift Serverless endpoint.

Find the best performance for your workloads

The performance results presented in this post are based on benchmarks derived from the industry-standard TPC-DS and TPC-H benchmarks, and have the following characteristics:

  • The schema and data of Iceberg tables are used unmodified from TPC-DS. Tables are partitioned to reflect real-world data organization patterns.
  • The queries are generated using the official TPC-DS and TPC-H kits with query parameters generated using the default random seed of the kits.
  • The TPC-DS test includes all 99 TPC-DS SELECT queries. It doesn’t include maintenance and throughput steps. The TPC-H test includes all 22 TPC-H SELECT queries.
  • Benchmarks are run out of the box: no manual tuning or stats collection is done for the workloads.

In the following sections, we discuss key performance improvements delivered in 2025.

Faster data lake scans

To improve data lake read performance, the Amazon Redshift team built a completely new scan layer designed from the ground-up for data lakes. This new scan layer includes a purpose-built I/O subsystem, incorporating smart prefetch capabilities to reduce data latency. Additionally, the new scan layer is optimized for processing Apache Parquet files, the most commonly used file format for Iceberg, through fast vectorized scans.

This new scan layer also includes sophisticated data pruning mechanisms that operate at both partition and file levels, dramatically reducing the volume of data that needs to be scanned. This pruning capability works in harmony with the smart prefetch system, creating a coordinated approach that maximizes efficiency throughout the entire data retrieval process.

JIT ANALYZE for Iceberg tables

Unlike traditional data warehouses, data lakes often lack comprehensive table- and column-level statistics about the underlying data, making it challenging for the planner and optimizer in the query engine to choose up-front which execution plan will be most optimal. Sub-optimal plans can lead to slower and less predictable performance.

JIT ANALYZE is a new Amazon Redshift feature that automatically collects and uses statistics for Iceberg tables during query execution—minimizing manual statistics collection while giving the planner and optimizer in the query engine the information it needs to generate optimal query plans. The system uses intelligent heuristics to identify queries that will benefit from statistics, performs fast file-level sampling using Iceberg metadata, and extrapolates population statistics using advanced techniques.

JIT ANALYZE delivers out-of-the-box performance nearly equal to queries that have pre-calculated statistics, while providing the foundation for many other performance optimizations. Some TPC-DS queries improved by 50 times faster with these statistics.

Query optimizations

For correlated subqueries such as those that contain EXISTS/IN clauses, Amazon Redshift uses decorrelation rules to rewrite the queries. In many cases, these decorrelation rules were not producing optimal plans, resulting in query execution performance regressions. To address this, we introduced a new internal join type, SEMI JOIN, and a new decorrelation rule based on this join type. This decorrelation rule helps in producing the most optimal plans, thereby improving execution performance. For instance, one of the TPC-DS queries that contains EXIST clause ran 7 times faster with this optimization.

We introduced distributed Bloom filter optimization for data lake workloads. Distributed Bloom filters create Bloom filters locally in every compute node and then distributes them to every other node. Distributing Bloom filters can significantly reduce the amount of data that needs to be sent over the network for the join by filtering out the tuples earlier. This provides good performance gains for large, complex data lake queries that process and join large amounts of data.

Conclusion

These performance improvements for Iceberg workloads represent a major leap forward in Redshift data lake capabilities. By focusing on out-of-the-box performance, we’ve made it straightforward to achieve exceptional query performance without complex tuning or optimization.

These improvements demonstrate the power of deep technical innovation combined with practical customer focus. JIT ANALYZE reduces the operational burden of statistics management while providing optimal query planning information. The new Redshift data lake query engine on Redshift Serverless was rewritten from the ground up for best-in-class scan performance, and lays the groundwork for more advanced performance optimizations. Semi-join optimizations tackle some of the most challenging query patterns in analytical workloads. You can run complex analytical workloads on your Iceberg data and get fast, predictable query performance.

Amazon Redshift is committed to being the best analytics engine for data lake workloads, and these performance optimizations represent our continued investment in that goal.

To learn more about Amazon Redshift and its performance capabilities, visit the Amazon Redshift product page. To get started with Redshift, you can try Amazon Redshift Serverless and start querying data in minutes without having to set up and manage data warehouse infrastructure. For more details on performance best practices, see the Amazon Redshift Database Developer Guide. To stay up-to-date with the latest developments in Amazon Redshift, subscribe to the What’s New in Amazon Redshift RSS feed.


Special thanks to this post’s contributors: Martin Milenkoski, Gerard Louw, Konrad Werblinski, Mengchu Cai, Mehmet Bulut, Mohammed Alkateb, and Sanket Hase

Accelerate data lake operations with Apache Iceberg V3 deletion vectors and row lineage

Post Syndicated from Ron Ortloff original https://aws.amazon.com/blogs/big-data/accelerate-data-lake-operations-with-apache-iceberg-v3-deletion-vectors-and-row-lineage/

Organizations building petabyte-scale data lakes face increasing challenges as their data grows. Batch updates and compliance deletes create a proliferation of positional delete files, slowing downstream data pipelines and driving up storage costs. Tracking data changes for audit trails and incremental processing requires custom, engine-specific implementations that add complexity and maintenance burden. As data volumes scale, these challenges compound, leaving data teams juggling custom solutions and increasing operational costs just to maintain data freshness and compliance.

Apache Iceberg V3 addresses these challenges with two new capabilities: deletion vectors and row lineage. AWS now delivers these capabilities across Apache Spark on Amazon EMR 7.12, AWS Glue, Amazon SageMaker notebooks, Amazon S3 Tables, and the AWS Glue Data Catalog, giving you a complete, integrated V3 experience without custom implementation. This means faster writes, lower storage costs, comprehensive audit trails, and efficient incremental processing, all working seamlessly across your entire data lake architecture.

In this post, we walk you through the new capabilities in Iceberg V3, explain how deletion vectors and row lineage address these challenges, explore real-world use cases across industries, and provide practical guidance on implementing Iceberg V3 features across AWS analytics, catalog, and storage services.

What’s new in Iceberg V3

Iceberg V3 introduces new capabilities and data types. Two key capabilities that address the challenges discussed earlier are deletion vectors and row lineage.

Deletion vectors replace positional delete files with an efficient binary format stored as Puffin files. Instead of creating separate delete files for each delete operation, the deletion vector consolidates these delete references to a single delete vector per data file, rather than a delete reference file per deleted row. During query execution, engines efficiently filter out deleted rows using these compact vectors, maintaining query performance while removing the need to merge multiple delete files.

This avoids write amplification from random batch updates and GDPR compliance deletes, significantly reducing the overhead of maintaining fresh data. High-frequency update workloads can see immediate improvements in write performance and reduced storage costs from fewer small delete files. Additionally, having fewer small delete files reduces table maintenance costs for compaction operations.

Row lineage enables precise change tracking at the row level with full auditability. Row lineage adds metadata fields to each data file that track when rows were created and last modified. The _row_id field uniquely identifies each row, and the _last_updated_sequence_number field tracks the snapshot when the row was last modified. These fields enable efficient change tracking queries without scanning entire tables, and they’re automatically maintained by the Iceberg specification without requiring custom code.

Before row lineage, change tracking in Iceberg provided only the net changes between snapshots, making it difficult to track individual record modifications. Row lineage metadata fields can now be queried to return all incremental changes, giving you full fidelity for auditing data modifications and regulatory compliance. For data transformations, your downstream systems can process changes incrementally, speeding up data pipelines and reducing compute costs for change data capture (CDC) workflows. Row lineage is engine agnostic, interoperable, and built into the Iceberg V3 specification, alleviating the need for custom, engine-specific change tracking implementations.

Real-world use cases

The new Iceberg V3 capabilities address critical challenges across multiple industries:

  • Marketing and advertising services organizations – You can now efficiently handle GDPR right-to-be-forgotten requests and regulatory compliance deletes without the write amplification that previously degraded pipeline performance. Row lineage provides complete audit trails for data modifications, meeting strict regulatory requirements for data governance.
  • Ecommerce platforms processing millions of product updates and inventory changes daily – You can maintain data freshness while reducing storage costs. Deletion vectors enable faster upsert operations, helping teams meet aggressive SLA requirements during peak shopping periods.
  • Healthcare and life sciences companies – You can track patient data modifications with precision for compliance purposes while efficiently processing large-scale genomic datasets. Row lineage provides the detailed change history required for clinical trial audits and regulatory submissions.
  • Media and entertainment providers managing large catalogs of user viewing data – You can efficiently process incremental changes for recommendation engines. Row lineage enables downstream analytics systems to process only changed records, reducing compute costs in incremental processing scenarios.

Get started with Iceberg V3

To take advantage of deletion vectors for optimized writes and row lineage for built-in change tracking in Iceberg V3, set the table property format-version = 3 during table creation. Alternatively, setting this property on an existing Iceberg V2 table atomically upgrades the table without data rewrites. Before creating or upgrading V3 tables, make sure the Iceberg engines in your solution are V3-compatible. Refer to Apache Iceberg V3 on AWS for more details.

Create a new V3 table with Apache Spark on Amazon EMR 7.12

The following code creates a new table named customer_data. Setting the table property format-version = 3 creates a V3 table. If the format-version table property is not explicitly set, a V2 table is created. V2 is currently the Iceberg default table version. Setting write.delete.mode, write.update.mode, and write.merge.mode to merge-on-read configures Spark to write deletion vectors for delete, update, or merge statements performed on the table.

CREATE TABLE customer_data (
customer_id bigint,
name string,
email string,
last_purchase timestamp,
total_spent decimal(10,2)
)
USING iceberg
TBLPROPERTIES (
'format-version' = '3',
'write.delete.mode' = 'merge-on-read',
'write.update.mode' = 'merge-on-read',
'write.merge.mode' = 'merge-on-read'
)

Run the following code to insert records into the customer_data table:

INSERT INTO customer_data VALUES
 (1, 'Alejandro Rosalez', '[email protected]', TIMESTAMP '2025-11-24 18:55:27', 42.97)
,(2, 'Akua Mansa', '[email protected]', TIMESTAMP '2025-11-24 17:55:27', 25.02)
,(3, 'Ana Carolina Silva','[email protected]', TIMESTAMP '2025-11-24 16:55:27', 43.67)
,(4, 'Arnav Desai','[email protected]', TIMESTAMP '2025-11-24 15:55:27', 98.32)
,(5, 'Carlos Salazar','[email protected]', TIMESTAMP '2025-11-24 12:55:27', 76.45)

Delete a record where customer_id = 5 to generate a delete file:

DELETE 
  FROM customer_data 
  WHERE customer_id = 5

Updating a record with the following update statement also generates a delete file:

UPDATE customer_data
  SET name = 'Mansa Akua' 
  WHERE customer_id = 2

The last part of this example queries the manifest’s metadata table to verify delete files were produced:

SELECT added_snapshot_id
      ,sum(added_delete_files_count) as added_delete_files_count 
FROM customer_data.manifests 
GROUP BY added_snapshot_id 
ORDER BY added_snapshot_id

This query will result in three records returned, as shown in the following screenshot. The added_delete_files_count for the first snapshot that inserts records should be 0. The next two snapshots for the corresponding delete and update statements should have 1 each for added_delete_files_count value.

Query row lineage for change tracking

Row lineage is automatically enabled on V3 tables. The following example includes row lineage metadata fields and an example of how to query table changes after a row lineage sequence number:

SELECT
customer_id,
name,
email,
_row_id,
_last_updated_sequence_number
FROM customer_data
WHERE _last_updated_sequence_number > 0
ORDER BY _last_updated_sequence_number, _row_id

Running this query after the previous insert, update, and delete statements returns four records, as shown in the following screenshot. The deleted record is removed. The _last_updated_sequence_number is 3 for the update to customer_id = 2.

Upgrade an existing V2 table

You can upgrade your existing V2 tables to V3 with the following command:

ALTER TABLE existing_customer_data
SET TBLPROPERTIES ('format-version' = '3')

When you upgrade a table from V2 to V3, several important operations occur atomically:

  • A new metadata snapshot is created atomically, resulting in no data loss.
  • Existing Parquet data files are reused without modification.
  • Row-lineage fields (_row_id and _last_updated_sequence_number) are added to the table metadata.
  • The next compaction operation will remove old V2 positional delete files. If new deletion vector files are generated before compaction runs, they will merge existing V2 positional delete files.
  • New modifications will automatically use V3’s deletion vector files.
  • The upgrade does not perform a historical backfill of row-lineage change tracking records.

The upgrade process is synchronous and completes in seconds for most tables. If the upgrade fails, an error message is returned immediately, and the table remains in its V2 state.

Getting the most from Iceberg V3

In this section, we share the key things we’ve learned from customers already using these features.

Know your workload pattern

Deletion vectors work best when you’re doing lots of writes, such as high-frequency updates, batch deletes, or CDC workloads making random non-append-only updates. If you’re writing more than you’re reading, deletion vectors will deliver immediate performance gains. To unlock these benefits, set your table to merge-on-read mode for delete, update, and merge operations.

Let AWS handle compaction

Enable automatic compaction through the Data Catalog or use S3 Tables (on by default). You will get hands-free optimization without building custom maintenance jobs. Deletion vectors produce fewer delete files than positional deletes in Iceberg V2. Given a similar pattern and amount of modified records, V3 compaction should be quicker and cost less than V2.

Understand the importance of row lineage when using the V2 changelog

With the Spark changelog procedure in Iceberg V2, if a row gets inserted and then deleted between snapshots, it disappears from your change feed—you never see it. Iceberg V3 row lineage captures both operations because _last_updated_sequence_number updates on each modification. This full fidelity is important for audit trails and regulatory compliance where you need to prove what happened to every record. Performance-wise, the V2 changelog requires scanning and merging delete files to compute changes—that’s compute you’re paying for on every read. V3 row lineage stores metadata fields directly on each row, so filtering by _last_updated_sequence_number is a simple metadata scan.

Test before you upgrade

Iceberg V3 upgrades are atomic and fast, but test in dev first. Make sure all your query engines support Iceberg V3 before upgrading shared tables—mixing V2 and V3 engines causes headaches. After upgrading, keep a few V2 snapshots around temporarily for time-travel queries while you validate performance.

Conclusion

Iceberg V3 support across AWS analytics, catalog, and storage services marks a significant advancement in data lake capabilities. By combining deletion vectors’ write optimization with row lineage’s comprehensive change tracking, you can build more efficient, auditable, and cost-effective data lakes at scale. The seamless interoperability across AWS services makes sure your data lake architecture remains flexible and future-proof.

To learn more about AWS support for Iceberg V3, refer to Using Apache Iceberg on AWS.

To learn more about building modern data lakes with Iceberg on AWS, refer to Analytics on AWS.


About the authors

Ron Ortloff

Ron Ortloff

Ron is a Principal Product Manager at AWS.

AWS Private Certificate Authority now supports partitioned CRLs

Post Syndicated from Kartik Bhatnagar original https://aws.amazon.com/blogs/security/aws-private-certificate-authority-now-supports-partitioned-crls/

Public Key Infrastructure (PKI) is essential for securing and establishing trust in digital communications. As you scale your digital operations, you’ll issue and revoke certificates. Revoking certificates is useful especially when employees leave, migrate to a new certificate authority hierarchy, meet compliance, and respond to security incidents. Use the Certificate Revocation List (CRL) or Online Certificate Status Protocol (OCSP) method to track revoked certificates. You can use Amazon Web Services (AWS) Private Certificate Authority (AWS Private CA) to create a certificate authority (CA), which publishes revocation information through these methods so that systems can verify certificate validity.

As enterprises continue to scale their operations, they face limitations when using complete CRLs to issue and revoke more than 1 million certificates. The workaround of increasing CRL file sizes isn’t viable, because many applications can’t process large CRL files (with some needing a 1 MB maximum). Furthermore, alternative solutions like OCSP may be rejected by major trust stores and browser vendors due to privacy concerns and compliance requirements. These constraints significantly impact your ability to scale PKI infrastructure efficiently while maintaining security and compliance standards.

Feature release: Addressing challenges

AWS Private CA addresses these challenges with partitioned CRLs, which enable the issuance and revocation of up to 100 million certificates per CA. This feature distributes revocation information across multiple smaller, manageable CRL partitions, each maintaining a maximum size of 1 MB for more effective application compatibility. At the time of issuance, certificates are automatically bound to specific CRL partitions through a critical Issuer Distribution Point (IDP) extension, which contains a unique URI identifying the partition. Validation works by comparing the CRL URI in the certificate’s CRL Distribution Point (CDP) extension against the CRL’s IDP extension, which provides accurate certificate validation.

Partitioned CRL provides automatic scaling of certificate issuance limits from 1M to 100M certificates per CA, support for both new and existing CAs, flexible configuration options for CRL naming and paths, backward compatibility by preserving existing complete CRL functionality while offering partitioned CRL as an optional feature, and compliance with industry standards such as RFC5280 while maintaining security and operational efficiency.

Configuring Partitioned CRLs in AWS Private CA

You can configure Partitioned CRLs for existing CAs in AWS Private CA by using the following steps.

  1. Choose Private certificate authorities in the left navigation bar.
  2. Choose the hyperlink in the Subject column that is your CA to go into its details.

    Note: Verify that you are in the correct AWS Region.

    Figure 1: Certificate Authority selection

    Figure 1: Certificate Authority selection

  3. Choose the Revocation configuration tab and you should observe the CRL distribution enabled or disabled. If it is disabled, then you should enable it in the next steps.
    Figure 2: Certification Authority general configuration information

    Figure 2: Certification Authority general configuration information

  4. Choose Edit.
  5. Check the checkbox of Activate CRL distribution.

    If CRL distribution was enabled already, then skip to step 7.

  6. Under S3 bucket URI, choose an existing bucket from the list. You can observe detailed steps listed in Step 6 of the instructions in Create a private CA in AWS Private CA.

    You must verify that BPA is disabled for the account and for the bucket, and you must manually attach a policy to it before you can begin generating CRLs. Use one of the policy patterns described in Access policies for CRLs in Amazon S3. For more information, go to Adding a bucket policy using the Amazon S3 console.

  7. Expand CRL settings for more configuration options.
  8. Check the Enable partitioning checkbox to enable partitioning of CRLs. This creates a partitioned CRL.

    If you don’t enable partitioning, then a complete CRL is created and your CA is subject to the limit of 1M issued or revoked certificates. For more information, go to AWS Private CA quotas.

    Figure 3: Certificate revocation options

    Figure 3: Certificate revocation options

  9. Choose Save changes.
  10. CRL distribution shows as enabled with partitioned CRLs. The limit of 1M automatically updates to 100M per CA.
    Figure 4: Certificate revocation configuration

    Figure 4: Certificate revocation configuration

Conclusion

The AWS Private CA partitioned CRLs can deliver substantial benefits across multiple dimensions. From a security perspective, the feature maintains certificate validation while supporting comprehensive revocation capabilities for up to 100M certificates per CA. Therefore, you can respond effectively to security incidents or key compromises. Operationally, it reduces CA rotation, lessening administrative overhead and streamlining PKI management. Furthermore, maintaining CRL partition sizes at 1 MB provides broad compatibility with applications while supporting automated partition management. Moreover, this makes it particularly valuable when you need scalable, standards-compliant certificate management. Regarding compliance, you can use the feature to comply with multiple industry requirements: it supports WebTrust principles and criteria and ETSI TSP standards, maintains compatibility with RFC5280, aligns with browser trust store requirements for both CRL and OCSP support, and provides the flexibility needed for emerging standards such as Matter.

Lastly, you can maximize the value of your general purpose or short-lived CA while all certificates remain revocable by enabling Partitioned CRL for no added charge on top of AWS Private CA and Amazon Simple Storage Service (Amazon S3).

Start creating your CA in AWS Private CA using AWS Management Console.

If you have feedback about this post, submit comments in the Comments section below.

Kartik Bhatnagar

Kartik Bhatnagar

Kartik is a San Francisco-based Solutions Architect at AWS, specializing in data security. With experience serving both startups and enterprises across fintech, healthcare, and media industries as a DevOps Engineer and Systems Architect, he helps customers design secure, scalable AWS solutions. Off-duty, he enjoys cricket, tennis, food hopping, and hiking.

How Octus achieved 85% infrastructure cost reduction with zero downtime migration to Amazon OpenSearch Service

Post Syndicated from Vaibhav Sabharwal original https://aws.amazon.com/blogs/big-data/how-octus-achieved-85-infrastructure-cost-reduction-with-zero-downtime-migration-to-amazon-opensearch-service/

As data volumes continue to grow exponentially, there is increasing pressure to optimize search infrastructure costs while maintaining the high performance and reliability that mission-critical workloads demand. Many companies find themselves managing complex, expensive search systems that require significant operational overhead and limit their ability to scale efficiently. The challenge becomes even more acute when organizations need to migrate between search systems, a process that traditionally involves substantial downtime, complex data synchronization, and significant impact on business operations. Enterprise applications cannot afford service interruptions that could impact customer experiences, business intelligence, or operational continuity. Migration strategies need to deliver cost optimization and operational improvements while maintaining zero downtime and facilitating complete data integrity throughout the transition process.

Founded in 2013, Octus, formerly Reorg, is the essential credit intelligence and data provider for the world’s leading buy side firms, investment banks, law firms and advisory firms. By surrounding unparalleled human expertise with proven technology, data and AI tools, Octus unlocks powerful truths that fuel decisive action across financial industries.

This post highlights how Octus migrated its Elasticsearch workloads running on Elastic Cloud to Amazon OpenSearch Service. The journey traces Octus’s shift from managing multiple systems to adopting a cost-efficient solution powered by OpenSearch Service. Along the way, we share the architecture choices and implementation strategies that made the migration successful. The result is uninterrupted service availability throughout migration, with improved performance and greater cost efficiency.

Strategic requirements

We identified several requirements that made Amazon OpenSearch Service the right choice for their migration:

  • Cost efficiency: The OpenSearch Service pricing model enabled us to optimize cloud spend without compromising performance.
  • Responsive support: AWS provided dependable, high-quality support to accelerate issue resolution and instill confidence.
  • Consistent reliability: OpenSearch Service provides an SLA up to 99.99% offering the reliability required for Octus’s mission-critical workloads.
  • Seamless migration with no query downtime: Migration Assistant for Amazon OpenSearch Service provided Octus with a migration path while maintaining uninterrupted query availability during the migration, facilitating business continuity.
  • Operational simplification: Consolidating onto AWS reduced infrastructure complexity while maintaining high security standards.

Solution overview

The Migration Assistant for Amazon OpenSearch Service provides a suite of tools to aid in Elasticsearch to OpenSearch Service migrations. Octus use the following capabilities for their migration:

  • Metadata migration: The tool enabled Octus to migrate dozens of indices with diverse mappings and settings. When a backward incompatibility was identified with timestamp metadata, a custom JavaScript transformation, integrated directly into the Migration Assistant tooling, was applied to automatically adjust the mappings across the indices and facilitate compatibility.
  • Historical data migration: Octus used Reindex-from-Snapshot to migrate the historical documents from a point-in-time snapshot of the source cluster, scaling this process without impacting the source cluster since the snapshot was stored in Amazon Simple Storage Service (Amazon S3). Reindex-from-Snapshot also enabled Octus to adjust the sharding scheme during migration, helping to optimize cluster performance on the target.
  • Live Traffic Replay: Once backfill was complete, Octus used Migration Assistant’s Traffic Replayer to send the captured live traffic (from the Traffic Capture Proxy) to the target cluster with required request transformations for OpenSearch Service compatibility, resulting in the target cluster containing the documents from the source cluster with updates being performed in real time.

The following diagram illustrates the implementation architecture diagram for this migration.


Figure 1 – Migration Assistant architecture with migration steps

For more information about the Migration Assistant for Amazon OpenSearch Service, visit the AWS Solutions home page.

Each node in the diagram correlates to the following steps in the migration process:

  1. Client traffic is directed to the existing cluster.
  2. An Application Load Balancer with capture proxies relays traffic to a source while replicating data to Amazon Managed Streaming for Apache Kafka (Amazon MSK).
  3. Using the migration console, a point-in-time snapshot is taken. Once the snapshot completes, the Metadata Migration Tool is used to establish indexes, templates, component templates, and aliases on the target cluster. With continuous traffic capture in place, Reindex-from-Snapshot, migrates data from the source.
  4. Once Reindex-from-Snapshot is complete, captured traffic is replayed from Amazon Managed Streaming for Apache Kafka (Amazon MSK) to the target cluster by Traffic Replayer.
  5. Performance and behavior of traffic sent to the source and target clusters are compared by reviewing logs and metrics.
  6. After confirming that the target cluster’s functionality meets expectations, clients are redirected to the new target.

Complete migration and optimization journey

Octus’s migration from Elastic Cloud to Amazon OpenSearch Service encompassed both the core migration effort and subsequent optimization phases. The goal was to successfully migrate the search infrastructure, applications, and data from Elastic Cloud to a new OpenSearch Service domain with minimal disruption, while continuously optimizing performance and costs based on real-world usage data.

Octus used their in-house custom infrastructure frameworks (their internal tooling for infrastructure automation) to build, deploy and monitor the target OpenSearch Service 1.3 domain, establishing a solid foundation for the migration. This approach used familiar internal processes while moving to the fully managed AWS service. Refer to AWS documentation to implement security best practices when using OpenSearch Service.

Pre-migration optimization

Prior to initiating the migration, Octus conducted optimization activities on the source Elasticsearch cluster to streamline the migration process. This included removing unused indexes that had accumulated over time and removing large documents that would unnecessarily extend migration duration and increase storage transfer costs. These preparatory steps significantly reduced the data volume requiring migration and minimized the overall migration complexity, enabling more efficient use of the Migration Assistant tools.

Technical constraints and version considerations

The migration involved specific version compatibility challenges that influenced the technical approach. The source Elasticsearch cluster was running version 7.17, and the Python client applications were also constrained to Elasticsearch 7.17 compatibility. To support the transition, the team used Reindex-from-Snapshot, which enables cross-system migrations by reindexing data from existing snapshots into a new OpenSearch Service cluster. RFS also rewrites indices created on older versions of Lucene, simplifying future upgrades to the latest version of OpenSearch Service. While evaluating a move to OpenSearch 1 or 2, Octus selected OpenSearch 1.3 as the target to minimize client-side changes and reduce migration complexity, while positioning themselves for simpler upgrades later.

The version selection particularly impacted the R application environment, as R language (an open-source programming language for statistical computing and data analysis) lacked native OpenSearch 1.3 client support. This constraint required Octus to develop a custom client solution using the ropensci/elastic library to integrate with the new OpenSearch Service domain. The Python environment presented similar challenges, where the Elasticsearch 7.17 client constraints necessitated careful consideration of the migration approach. These client compatibility concerns were among the factors that influenced the choice of Migration Assistant tools over traditional snapshot-based methods, as the Migration Assistant provided better support for managing version-specific client interactions during the transition.

Looking forward, Octus plans to upgrade to newer OpenSearch versions as their application stack evolves and client library support matures, so that they can leverage the latest features and performance improvements while maintaining the stability achieved through this migration.

Application modernization across multiple languages

The application changes represented a significant technical undertaking across multiple programming environments:

  • Legacy PHP systems (5.6 and Laravel 4.2): Octus handled mapping type deprecation on OpenSearch requests as specifying these mapping types are not supported, while continuing to use the elasticsearch connector library with username/password authentication.
  • Modern PHP applications (8.1 and Laravel 9): These underwent more comprehensive changes, replacing the elasticsearch/elasticsearch library with the opensearch-project/opensearch-php client and leveraging IAM authentication to connect to the clusters.
  • Python environment: Applications spanning versions 3.8, 3.10, 3.11, and 3.13 with Django frameworks 2.1, 3.2, and 5.2 required replacing the elasticsearch library with opensearch-py and transitioning to IAM authentication.
  • R applications: For R 4.5.1 applications, Octus utilized a custom library ropensci/elastic to facilitate compatibility.

Traffic routing and enhanced monitoring

To facilitate the migration, Octus redirected their existing clients to route requests to the source cluster through Migration Assistant’s Traffic Capture Proxy, migrating the data from live traffic to their target cluster.

The monitoring infrastructure underwent significant enhancement during this process. Octus’s observability infrastructure monitors the overall health of OpenSearch Service clusters which includes cluster manager and data nodes, network, data storage, security and IAM access. It also monitors the indexing and search performance of their applications. This alleviated the need for a separate monitoring cluster as logs and metrics were shipped directly to Datadog, significantly improving observability. The Datadog monitors were defined using Infrastructure-as-Code and integrated seamlessly into their infrastructure frameworks.

Cutover and initial results

The Site Reliability Engineering team meticulously planned the release, achieving a successful migration from Elasticsearch to OpenSearch Service and cutover of the Elasticsearch client to the OpenSearch Service clients with no downtime for the system application and zero data loss. The initial migration phase resulted in a 52% cost reduction while achieving operational benefits including zero downtime for the system app, no data loss, full Infrastructure-as-Code implementation for infrastructure and monitoring, and enhanced observability.

Post-migration optimization

Following the migration, Octus conducted comprehensive optimization based on operational data from production and other environments in the new OpenSearch Service setup. This real-world usage data provided valuable insights into actual resource consumption, enabling informed decisions regarding further cluster resizing.

Through usage metric analysis and strategic resizing, Octus aligned cluster size more precisely with operational needs, facilitating continued performance while minimizing expenditure. This optimization phase delivered an additional 33% cost reduction compared to the original Elastic Cloud costs, bringing the total reduction to 85% while maintaining consistent and optimal performance.

Operational monitoring

Octus uses Datadog to monitor both search and indexing latency providing real-time visibility into Amazon OpenSearch Service cluster performance. The following screenshot showcases how custom Datadog dashboards provide a live view of the OpenSearch Service clusters. This visualization offers both a high-level overview and detailed insights into the ingestion process, helping us understand the storage and document count. The bottom half of the dashboard presents a time-series view of individual node health and performance metrics like read and write latency, throughput and IOPS.


Figure 2 – DataDog dashboards

Migration observability

Migration Assistant for Amazon OpenSearch Service provides several dashboards to observe and validate the progress of a migration. By using these observability features customers can track both backfill and live capture and replay progress, facilitating confidence before switching production workloads to the target cluster.The following graphs are an example from Octus’s migration, where approximately 4TB of data was migrated in about 9 hours (from 08:00 to 17:00).


Figure 3 – Backfill progress by disk usage


Figure 4 – Backfill progress by searchable documents

Once the backfill is complete, the captured traffic is replayed to synchronize ongoing activity between the source and target clusters.

At the time the backfill finished (around 17:00), the target cluster was approximately 467 minutes behind the source. The replay process rapidly reduced this lag by processing captured traffic at a faster rate than it was originally ingested at the source.


Figure 5 – Replay lag after backfill completion

When the lag time reached 0, the target cluster was fully in sync and production traffic could safely be rerouted. Octus chose to observe replayed traffic on the target for several days before making the final switchover.

Achieving excellence

Octus’s migration to Amazon OpenSearch Service has yielded remarkable results:

  • Scalability – Octus has almost doubled the number of documents available for Q&A across three environments in days instead of weeks. Their use of Amazon Elastic Container Service (Amazon ECS) with AWS Fargate with auto scaling rules and controls gives them elastic scalability for their services during peak usage hours.
  • Cost reduction – By moving away from Elastic Cloud to OpenSearch Service, Octus’s monthly infrastructure costs are now 85% lower.
  • Enhanced search performance – Octus maintained consistent response times throughout the migration with no negative impact on latency, while achieving a 20% improvement in query throughput and overall search performance.
  • Zero downtime – Octus experienced zero downtime during migration and 100% uptime overall for the whole application.
  • Reduced operational overhead – Post-migration, Octus’s DevOps and SRE teams see 30% less maintenance burden and overheads. Supporting SOC2 compliance is also straightforward now that they’re using one system.
  • Accelerated timeline delivery – The entire migration was completed ahead of schedule, moving from planning to full completion in under one quarter.

“Moving from Elastic Cloud to Amazon OpenSearch Service was a key component of our broader strategy to minimize third-party dependencies and strengthen the reliability of Octus’ system infrastructure. Migration Assistant for Amazon OpenSearch Service enabled us to execute a seamless transition with zero data loss and virtually no downtime for our users.” – Vishal Saxena, CTO, Octus

Conclusion

In this post, we showed you how Octus successfully migrated their Elasticsearch workloads from Elastic Cloud to Amazon OpenSearch Service using the Migration Assistant for OpenSearch Service, achieving zero downtime and significant operational improvements.

The Migration Assistant for OpenSearch Service supported this complex migration through its comprehensive suite of tools. The Metadata Migration capability migrated dozens of indices with diverse mappings and settings, with custom JavaScript transformations handling backward incompatibilities. Reindex-from-Snapshot migrated the historical documents from point-in-time snapshots without impacting the source cluster, while also optimizing the sharding scheme for improved performance. Live Traffic Replay made sure the target cluster remained synchronized with real-time updates throughout the migration process.

The migration delivered substantial results across the dimensions. Octus achieved an 85% reduction in monthly infrastructure costs while nearly doubling the number of documents available for search across three environments. Search performance improved by 20% in query throughput with consistent response times and no negative impact on latency. The migration maintained zero downtime and 100% uptime for the entire application, with DevOps and SRE teams experiencing 30% less maintenance burden and operational overhead. The entire migration was completed ahead of schedule in under one quarter.

To learn more about the Migration Assistant for OpenSearch Service and how it can help you achieve similar results, visit the AWS Solutions home page.

Visit Octus to learn how we deliver rigorously verified intelligence at speed and create a complete picture for professionals across the entire credit lifecycle. Follow Octus on LinkedIn and X.


About the Authors

Harmandeep Sethi

Harmandeep Sethi

Harmandeep is Head of SRE Engineering and Infrastructure Frameworks at Octus. with nearly 10 years of experience leading high-performing teams in the implementation of large-scale systems. He has played a pivotal role in transforming and modernizing Octus’s Search Engine infrastructure and services by driving best practices in observability, resilience engineering, and the automation of operational processes through Infrastructure Frameworks.

Serhii Shevchenko

Serhii Shevchenko

Serhii is a Site Reliability Engineer at Octus. With 9 years of combined experience in software development and site reliability engineering, his expertise focuses on enhancing system reliability and performance. He was a key developer on the application side for the company’s critical migration from Elasticsearch Cloud to AWS OpenSearch. His planning was instrumental in executing the transition with zero client-facing downtime.

Govind Bajaj

Govind Bajaj

Govind is a Senior Site Reliability Engineer at Octus, specializing in architecting and implementing scalable infrastructure that supports high-performing engineering teams and critical systems. With over 8 years of experience, he excels at breaking down complex problems and turning them into practical, well-designed solutions, with a strong focus on building secure, observable, and resilient platforms.

Virendra Shinde

Virendra Shinde

Virendra is the Head of Platform at Octus, where he oversees cloud infrastructure, site reliability, and the core frameworks that power the Octus product suite. Before joining Octus, he spent two years at Grayscale Investments building an investor portal and data APIs from the ground up. Prior to that, he spent eight years at Blackstone leading multiple development teams. He holds a Master’s degree in Information Management from the University of Maryland.

Brian Presley

Brian Presley

Brian is a Software Development Manager at OpenSearch, leading teams behind OpenSearch Migrations and OpenSearch Serverless to build scalable, high-impact search and analytics solutions.

Andre Kurait

Andre Kurait

Andre is a Software Development Engineer II at AWS, based in Austin, Texas. He is currently working on Migration Assistant for Amazon OpenSearch Service. Prior to joining Amazon OpenSearch, Andre worked within Amazon Health Services. In his free time, Andre enjoys traveling, cooking, and playing in his church sport leagues. Andre holds Bachelor of the Science degrees from the University of Kansas in Computer Science and Mathematics.

Vaibhav Sabharwal

Vaibhav Sabharwal

Vaibhav is a Senior Solutions Architect at AWS based out of New York. He is passionate about learning new cloud technologies and assisting customers in building cloud adoption strategies, designing innovative solutions, and driving operational excellence. As a member of the Financial Services and Storage Technical Field Communities at AWS, he actively contributes to the collaborative efforts within the industry.

AWS Secrets Manager launches Managed External Secrets for Third-Party Credentials

Post Syndicated from Rohit Panjala original https://aws.amazon.com/blogs/security/aws-secrets-manager-launches-managed-external-secrets-for-third-party-credentials/

Although AWS Secrets Manager excels at managing the lifecycle of Amazon Web Services (AWS) secrets, managing credentials from third-party software providers presents unique challenges for organizations as they scale usage of their cloud applications. Organizations using multiple third-party services frequently develop different security approaches for each provider’s credentials because there hasn’t been a standardized way to manage them. When storing these third-party credentials in Secrets Manager, organizations frequently maintain additional metadata within secret values to facilitate service connections. This approach requires updating entire secret values when metadata changes and implementing provider-specific secret rotation processes that are manual and time consuming. Organizations looking to automate secret rotation typically develop custom functions tailored to each third-party software provider, requiring specialized knowledge of both third-party and AWS systems.

To help customers streamline third-party secrets management, we’re introducing a new feature in AWS Secrets Manager called managed external secrets. In this post, we explore how this new feature simplifies the management and rotation of third-party software credentials while maintaining security best practices.

Introducing managed external secrets

AWS Secrets Manager has a proven track record of helping customers secure and manage secrets for AWS services such as Amazon Relational Database Service (Amazon RDS) or Amazon DocumentDB through managed rotation capabilities. Building on this success, Secrets Manager now introduces managed external secrets, a new secret type that extends this same seamless experience to third-party software applications like Salesforce, simplifying secret management challenges through standardized formats and automated rotation.

You can use this capability to store secrets vended by third-party software providers in predefined formats. These formats were developed in collaboration with trusted integration partners to define both the secret structure and required metadata for rotation, eliminating the need for you to define your own custom storage strategies. Managed external secrets also provides automated rotation by directly integrating with software providers. With no rotation functions to maintain, you can reduce your operational overhead while benefiting from essential security controls, including fine-grained permissions management using AWS Identity and Access Management (IAM), secret access monitoring through Amazon CloudWatch and AWS CloudTrail, and automated secret-specific threat detection through Amazon GuardDuty. Moreover, you can implement centralized and consistent secret management practices across both AWS and third-party secrets from a single service, eliminating the need to operate multiple secrets management solutions at your organization. Managed external secrets follows standard Secrets Manager pricing, with no additional cost for using this new secret type.

Prerequisites

To create a managed external secret, you need an active AWS account with appropriate access to Secrets Manager. The account must have sufficient permissions to create and manage secrets, including the ability to access the AWS Management Console or programmatic access through the AWS Command Line Interface (AWS CLI) or AWS SDKs. At minimum, you need IAM permissions for the following actions: secretsmanager:DescribeSecret, secretsmanager:GetSecretValue, secretsmanager:UpdateSecret, and secretsmanager:UpdateSecretVersionStage.

You must have valid credentials and necessary access permissions for the third-party software provider you plan to have AWS manage secrets for.

For secret encryption, you must decide whether to use an AWS managed AWS Key Management Service (AWS KMS) key or a customer managed KMS key. For customer managed keys, make sure you have the necessary key policies configured. The AWS KMS key policy should allow Secrets Manager to use the key for encryption and decryption operations.

Create a managed external secret

Today, managed external secrets supports three integration partners: Salesforce, Snowflake, and BigID. Secrets Manager will continue to expand its partner list and more third-party software providers will be added over time. For the latest list, refer to Integration Partners.

To create a managed external secret, follow the steps in the following sections.

Note: This example demonstrates the steps for retrieving Salesforce External Client App Credentials, but a similar process can be followed for other third-party vendor credentials integrated with Secrets Manager.

To select secret type and add details:

  1. Go to the Secrets Manager service in the AWS Management Console and choose Store a new secret.
  2. Under Secret type, select Managed external secret.
  3. In the AWS Secrets Manager integrated third-party vendor credential section, select your provider from the available options. For this walkthrough, we select Salesforce External Client App Credential.
  4. Enter your configurations in the Salesforce External Client App Credential secret details section. The Salesforce External Client App credentials consist of several key components:
    1. The Consumer key (client ID), which serves as the credential identifier for OAuth 2.0. You can retrieve the consumer key directly from the Salesforce External Client App Manager OAuth settings.
    2. The Consumer secret (client secret), which functions as the private password for OAuth 2.0 authentication. You can retrieve the consumer secret directly from the Salesforce External Client App Manager OAuth settings.
    3. The Base URI, which is your Salesforce org’s base URL (formatted as https://MyDomainName.my.salesforce.com), is used to interact with Salesforce APIs.
    4. The App ID, which identifies your Salesforce External Client Apps (ECAs) and can be retrieved by calling the Salesforce OAuth usage endpoint.
    5. The Consumer ID, which identifies your Salesforce ECA, can be retrieved by calling the Salesforce OAuth credentials by App ID endpoint. For a list of commands, refer to Stage, Rotate, and Delete OAuth Credentials for an External Client App in the Salesforce documentation.
  5. Select the Encryption key from the dropdown menu. You can use an AWS managed KMS key or a customer managed KMS key.
  6. Choose Next.
Figure 1: Choose secret type

Figure 1: Choose secret type

To configure a secret:

  1. In this section, you need to provide information for your secret’s configuration.
  2. In Secret name, enter a descriptive name and optionally enter a detailed Description that helps identify the secret’s purpose and usage. You also have additional configuration choices available: you can attach Tags for better resource organization, set specific Resource permissions to control access, and select Replicate secret for multi-Region resilience.
  3. Choose Next.
Figure 2: Configure secret

Figure 2: Configure secret

To configure rotation and permissions (optional):

In the optional Configure rotation step, the new secret configuration introduces two key sections focused on metadata management, which are stored separately from the secret value itself.

  1. Under Rotation metadata, specify the API version your Salesforce app is using. To find the API version, refer to List Available REST API Versions in the Salesforce documentation. Note: The minimum version needed is v65.0.
  2. Select an Admin secret ARN, which contains the administrative OAuth credentials that are used to rotate the Salesforce client secret.
  3. In the Service permissions for secret rotation section, Secrets Manager automatically creates a role with necessary permissions to rotate your secret values. These default permissions are transparently displayed in the interface for review when you choose view permission details. You can deselect the default permissions for more granular control over secret rotation management.
  4. Choose Next.
Figure 3: Configure rotation

Figure 3: Configure rotation

To review:

In the final step, you’ll be presented with a summary of your secret’s configuration. On the Review page, you can verify parameters before proceeding with secret creation.

After confirming that the configurations are correct, choose Store to complete the process and create your secret with the specified settings.

Figure 4: Review

Figure 4: Review

After successful creation, your secret will appear on the Secrets tab. You can view, manage, and monitor aspects of your secret, including its configuration, rotation status, and permissions. After creation, review your secret configuration, including encryption settings and resource policies for cross-account access, and examine the sample code provided for different AWS SDKs to integrate secret retrieval into your applications. The Secrets tab provides an overview of your secrets, allowing for central management of secrets. Select your secret to view Secret details.

Figure 5: View secret details

Figure 5: View secret details

Your managed external secret has been successfully created in Secrets Manager. You can access and manage this secret through the Secrets Manager console or programmatically using AWS APIs.

Onboard as an integration partner with Secrets Manager

With the new managed external secret type, third-party software providers can integrate with Secrets Manager and offer their customers a programmatic way to securely manage secrets vended by their applications on AWS. This integration provides their customers with a centralized solution for managing both the lifecycle of AWS and third-party secrets, including automatic rotation capabilities from the moment of secret creation. Software providers like Salesforce are already using this capability.

“At Salesforce, we believe security shouldn’t be a barrier to innovation, it should be an enabler. Our partnership with AWS on managed external secrets represents security-by-default in action, removing operational burden from our customers while delivering enterprise-grade protection. With AWS Secrets Manager now extending to partners and automated zero-touch rotation eliminating human risk, we’re setting a new industry standard where secure credentials become seamless without specialized expertise or additional costs.” — Jay Hurst, Sr. Vice President, Product Management at Salesforce

There is no additional cost to onboard with Secrets Manager as an integration partner. To get started, partners must follow the process listed on the partner onboarding guide. If you have questions about becoming an integration partner, contact our team at [email protected] with Subject: [Partner Name] Onboarding request.

Conclusion

In this post, we introduced managed external secrets, a new secret type in Secrets Manager that addresses the challenges of securely managing the lifecycle of third-party secrets through predefined formats and automated rotation. By eliminating the need to define custom storage strategies and develop complex rotation functions, you can now consistently manage your secrets—whether from AWS services, custom applications, or third-party providers—from a single service. Managed external secrets provide the same security features as standard Secrets Manager secrets, including fine-grained permissions management, observability, and compliance controls, while adding built-in integration with trusted partners at no additional cost.

To get started, refer to the technical documentation. For information on migrating your existing partner secrets to managed external secrets, see Migrating existing secrets. The feature is available in all AWS Regions where AWS Secrets Manager is available. For a list of Regions where Secrets Manager is available, see the AWS Region table. If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on Secrets Manager re:Post or contact AWS Support.

Rohit Panjala

Rohit is a Security Specialist at AWS, focused on data protection and cryptography services. He is responsible for developing and implementing go-to-market (GTM) strategies and driving customer and partner adoptions for AWS data protection services on a global scale. Before joining AWS, he worked in security product management at IBM and electrical engineering roles. He holds a BS in engineering from The Ohio State University.

Rochak Karki

Rochak is a Security Specialist Solutions Architect at AWS, focusing on threat detection, incident response, and data protection to help customers build secure environments. Rochak is a US Army veteran and holds a BS in engineering from the University of Wyoming. Outside of work, he enjoys spending time with family and friends, hiking, and traveling.

How potential performance upside with AWS Graviton helps reduce your costs further

Post Syndicated from Markus Adhiwiyogo original https://aws.amazon.com/blogs/compute/how-potential-performance-upside-with-aws-graviton-helps-reduce-your-costs-further/

Amazon Web Services (AWS) provides many mechanisms to optimize the price performance of workloads running on Amazon Elastic Compute Cloud (Amazon EC2), and the selection of the optimal infrastructure to run on can be one of the most impactful levers. When we started building the AWS Graviton processor, our goal was to optimize AWS Graviton features and capabilities to deliver a processor that provides the best price performance across a broad array of cloud workloads running on Amazon EC2. That goal continues to be our guiding principle, and today customers who adopt AWS Graviton-based EC2 instances see up to 40% better price performance on their cloud workloads when compared to equivalent non-Graviton EC2 instances. The price performance improvement is the result of both the performance improvement and the lower price in using AWS Graviton-based instances.

Price performance blends the cost of infrastructure with the amount of work you can achieve with infrastructure usage. After talking to many AWS Graviton customers, we’ve learned that the cost savings go beyond the lower AWS Graviton-based instances price. Many AWS Graviton customers told us that the performance increase from AWS Graviton allows them to consume fewer computing hours than comparable non-Graviton instances for equivalent workload throughput. In turn, this leads to further cost reduction.

The following are some of examples from our customers:

  • Pinterest achieved 47% cost savings and 38% savings on compute resources while reducing carbon emissions by 62% for its web API workload.
  • SAP powers its SAP HANA Cloud with AWS Graviton to enhance its price performance by 35% while lowering carbon impact by 45%.
  • Sprinklr improved their machine learning (ML) inference workloads’ throughput by up to 20% while reducing costs by up to 25%.

You can find more customer examples in the AWS Graviton testimonials page.

To help organizations capture similar benefits, we’ve enhanced the AWS Graviton Savings Dashboard (GSD) with new features that account for both pricing and performance improvements. In the following section we explore these new capabilities and how they can help optimize your infrastructure costs.

Understanding performance-driven cost optimization in the GSD

The GSD helps organizations identify ideal workloads for AWS Graviton migration through automated resource matching and data-driven visualizations. You can learn the GSD details and setup in this AWS compute post.

Although the dashboard has traditionally focused on calculating direct cost savings from the AWS Graviton pricing advantages, we’ve observed that customers often experience more benefits when their applications perform more efficiently on AWS Graviton processors, leading to decreased compute resource usage. To better reflect these real-world scenarios, we’ve enhanced the dashboard with new features highlighting Normalized Instance Hours (NIH) analysis capabilities so that you can model potential savings based on both pricing benefits and compute hour reductions. Although this tool helps estimate potential savings, actual performance improvements can only be determined by testing your specific workloads on AWS Graviton instances. Performance is always workload and use case specific, so we encourage you to test your AWS Graviton-based workloads using the Optimization and Performance Runbook to help you determine the actual possible NIH percent reduction.

Key dashboard components

This section outlines the following three key dashboard components: NIH reduction analysis, enhanced cost analysis visualizations, and detailed savings analysis.

NIH reduction analysis

The dashboard now features a new slider that lets you model potential cost savings by inputting the percentage reduction in NIH. Many organizations have found it challenging to calculate their total possible savings since the benefits come from two sources: the lower instance pricing of AWS Graviton and the reduced compute hours.

You can use the slider to model different cost scenarios by adjusting a theoretical NIH reduction between 0% and 40%. You can use this slider to input NIH reductions validated through your workload testing, model the combined impact of both pricing benefits and reduced compute hours, and explore different scenarios to help prioritize which workloads to test first.

Figure 1: NIH slider location

Figure 1: NIH slider location

Assume that your testing shows that your workload runs just as effectively with 15% fewer normalized instance hours on AWS Graviton. You can now plug that exact number into the slider to see your modeled savings combining both pricing differences and compute hour reductions. Although we’ve heard success stories of significant reductions from customers, we recommend starting your initial estimate with a conservative 10% baseline and adjusting based on your own testing results.

Enhanced cost analysis visualizations

The dashboard presents key visualizations that demonstrate the direct relationship between NIH reduction and cost savings. First, you see the Potential Graviton Base Savings from pricing differences alone. In the following diagram, we can observe an example of $61.54K of cost savings from migrating to equivalent AWS Graviton instances. Next, the Estimated Additional Savings Due to Performance in the same diagram shows $42.40K in savings if your performance testing confirms a 15% NIH reduction in your workload. Finally, the dashboard sums these two values into the Total Potential Graviton Savings of $103.94K. The Total Potential Graviton Savings helps visualize how both pricing benefits and any validated compute hour reductions could contribute to your overall savings.

Figure 2: Visualization with relationship between NIH reduction and cost savings

Figure 2: Visualization with relationship between NIH reduction and cost savings

The Amortized Cost Breakdown and Normalized Instance Hrs Breakdown charts in the following figure show 6-month historical trends, helping you spot patterns such as seasonal spikes or high-usage periods. These patterns can help you identify where even small efficiency improvements might yield significant savings, for example, workloads with consistently high usage or predictable peak periods that would be good candidates for testing.

Figure 3: Amortized Cost, NIH, and Total Potential Savings Breakdown charts

Figure 3: Amortized Cost, NIH, and Total Potential Savings Breakdown charts

Detailed savings analysis

Building on our commitment to help customers optimize cloud costs, we’ve enhanced the Potential Graviton Savings Details table with two columns focused on performance-based savings modeling. The Estimated Additional Savings Due to Performance column shows the modeled savings based on your chosen NIH reduction percentage, while Total Potential Graviton Savings combines this with the base pricing benefits.

Figure 4: Potential Graviton Savings Details table

Figure 4: Potential Graviton Savings Details table

As you examine your current instance family, you can observe both baseline AWS Graviton savings and these added saving opportunities clearly laid out in a comprehensive breakdown. The analysis presents your total savings potential in both dollar amounts and percentages. This allows you to build a compelling business case for migration. Although this detailed breakdown provides valuable planning insights, remember that actual savings may vary depending on your specific workload patterns, implementation approaches, and operational considerations.

Conclusion

The Graviton Savings Dashboard (GSD) serves as a powerful analytics tool that streamlines your journey to cost-effective cloud computing. The GSD provides clear visualizations and interactive features to help you understand and maximize potential savings when migrating to AWS Graviton-based instances. To further explore the new features, navigate to the GSD interactive demo, where you can model an example of potential savings using the NIH reduction slider and detailed cost breakdowns.

Ready to explore how AWS Graviton can transform your infrastructure costs? Visit the GSD page to deploy or update your GSD dashboard. Access implementation guides, such as the CFM Technical Implementation Playbook (CFM TIPs), and start optimizing your cloud spend today with the enhanced capabilities of the GSD.

Over 85,000 AWS customers have discovered the benefits of AWS Graviton, with many completing their adoptions in just hours. We have created this resource guide so that you can accelerate your AWS Graviton adoption with minimal effort and enjoy significant price performance benefits.

“What I always tell customers is one week, one application, one engineer, and see what you can do. They always are pleasantly surprised by how much progress they can make. If you’re out there and you haven’t yet moved to AWS Graviton, what are you waiting for? Let’s make it happen!”

Dave Brown, VP, AWS Compute & ML Services

Important note about performance testing
The GSD does not attempt to estimate the potential NIH percent reduction or your workload’s performance when transitioned to AWS Graviton. You can use it to perform what-if analysis of your potential savings for a projected NIH percent reduction. In the absence of this variable, GSD only considers the price delta between instance types and misses an important contributor to the overall savings potential of AWS Graviton from the performance upside. Compute performance is always workload and use case specific, so we encourage you to test your AWS Graviton-based workloads using the Optimization and Performance Runbook to help you determine the actual possible NIH percent reduction.

Enhancing API security with Amazon API Gateway TLS security policies

Post Syndicated from Anton Aleksandrov original https://aws.amazon.com/blogs/compute/enhancing-api-security-with-amazon-api-gateway-tls-security-policies/

As compliance frameworks evolve and cryptographic standards advance, organizations are looking for additional controls to improve their cloud security posture. One of the neccesary controls is a more granular TLS configuration, for example when regulatory requirements mandate disabling older ciphers like CBC or enforcing TLS 1.3 as a minimum version.

In this post, you will learn how the new Amazon API Gateway’s enhanced TLS security policies help you meet standards such as PCI DSS, Open Banking, and FIPS, while strengthening how your APIs handle TLS negotiation. This new capability increases your security posture without adding operational complexity, and provides you with a single, consistent way to standardize TLS configuration across your API Gateway infrastructure.

Overview

Previously, API Gateway offered limited control over TLS configuration, and only for custom domain names. Default endpoints used fixed security policies, which meant you often had to introduce additional infrastructure, such as custom Amazon CloudFront distributions, to meet your organization’s security or compliance requirements.

With this launch, you can configure TLS behavior directly on all REST API endpoint types, including Regional, edge-optimized, and private, and apply consistent TLS settings across both your APIs and their custom domain names. You can choose from predefined enhanced security policies to enforce the minimum TLS versions and cipher suites that your workloads require. For example, you can enforce TLS 1.3, use hardened TLS 1.2 without CBC ciphers, adopt FIPS-aligned suites for government workloads, or prepare for the future with policies that include post-quantum cryptography (PQC). The new security policies provide finer-grained control without adding operational complexity, helping you align your APIs with evolving security and compliance expectations.

Understanding API Gateway security policies

A security policy in API Gateway is a predefined combination of a minimum TLS version and a curated set of cipher suites. When a client connects to your REST API or custom domain name, API Gateway uses the selected policy to determine which protocol versions and ciphers it will accept during the TLS handshake. This gives you a predictable and enforceable way to control how clients establish encrypted connections to your APIs.

API Gateway supports two categories of security policies. Legacy policies, such as TLS_1_0 or TLS_1_2, remain available for backwards compatibility. Enhanced policies, identified by the SecurityPolicy_* prefix, provide stricter and more modern controls for regulated workloads, advanced governance, or cryptographic hardening. When you use an enhanced policy, you must also specify an endpoint access mode, which adds additional validation for how traffic reaches your API, as described in the following sections.

Enhanced policies follow a consistent naming patterns that helps you quickly understand what each policy enforces. For example, for REGIONAL and PRIVATE endpoint types, the following pattern applies:

SecurityPolicy_[TLS-Versions]_[Variant]_[YYYY-MM]

From this structure, you can identify the minimum TLS versions supported, any specialized cryptographic variants (such as FIPS, PFS, or PQ), and the release date of the policy. For example, SecurityPolicy_TLS13_1_3_2025_09 accepts only TLS 1.3 traffic, while SecurityPolicy_TLS13_1_2_PFS_PQ_2025_09 supports TLS 1.2 as lowest and TLS 1.3 as highest TLS version with forward secrecy and post-quantum enhancements.

Each policy maps to a curated combination of ciphers. For instance, SecurityPolicy_TLS13_1_3_2025_09 accepts only three TLS 1.3 cipher suites (TLS_AES_128_GCM_SHA256, TLS_AES_256_GCM_SHA384, and TLS_CHACHA20_POLY1305_SHA256) and rejects any other protocol versions or ciphers. For a full list of supported policies and ciphers, and naming pattern for the EDGE endpont type, see the API Gateway documentation.

How security policies apply to default endpoints and custom domains

You can use API Gateway to attach different security policies to your default API endpoint and custom domain names. During TLS negotiation, API Gateway selects the policy based on the Server Name Indication (SNI) value in the client’s TLS handshake, not the HTTP Host header. This means the policy depends on the hostname the client uses when initiating TLS.

For example, if a client connects directly to your default endpoint, such as:

https://abcdef1234.execute-api.us-east-1.amazonaws.com

API Gateway uses the policy attached to that default endpoint because the SNI value matches its hostname.

If the client instead connects through a custom domain name, such as:

https://api.example.com

API Gateway uses the policy attached to that custom domain. In this case, the SNI value api.example.com determines which policy is enforced.

This distinction is important even if you disable your default endpoint. TLS negotiation always occurs before API Gateway evaluates endpoint settings, so the default endpoint security policy still applies to clients that connect directly to its hostname. To avoid unexpected client behavior, you should keep the API and its custom domain name aligned with the same security policy whenever possible.

Understanding endpoint access mode

When you use an enhanced security policy (SecurityPolicy_*), you must also specify an endpoint access mode. Endpoint access mode defines how strictly API Gateway validates the network path a request takes before it reaches your API. This gives you an additional layer of governance and helps you prevent unauthorized or misrouted traffic.

You can choose between two modes:

  • BASIC mode provides standard API Gateway behavior. It is the recommended starting point when you migrate an existing API to an enhanced security policy. Clients can continue reaching your API as they do today, without additional validation.
  • STRICT mode adds enforcement checks to ensure that requests originate from the correct endpoint type, and TLS negotiation aligns with your configuration.

When you enable STRICT mode, API Gateway performs additional validations, such as:

  • The SNI and HTTP Host header values match
  • The request originates from the same endpoint type as your API (Regional, edge-optimized, or private)

If any of these validations fail, API Gateway rejects the request. STRICT is a viable choice when you need stronger security guarantees, such as when running regulated or sensitive workloads. See API Gateway documentation for additional details.

When you switch from BASIC to STRICT mode, it takes up to 15 minutes for the change to fully propagate. Your API remains available during this period. If your endpoint access mode is set to STRICT, you cannot change the endpoint type until you revert the mode back to BASIC.

Applying security policies to new and existing APIs

You can apply a security policy when you create a new REST API or custom domain name, or update an existing resource to use one of the enhanced SecurityPolicy_* options. When migrating existing APIs, the recommended approach is to start with BASIC mode, validate client behavior (SNI and HTTP Host header values match, request originates from the same endpoint type as your API), and then move to STRICT mode once you confirm compatibility.

The following code snippets illustrate how to apply security policies to different scenarios:

Create a REST API with a security policy and STRICT endpoint access mode

You can attach a security policy directly during API creation, removing the need for extra infrastructure just to control TLS negotiation.

aws apigateway create-rest-api \
  --name "your-private-api-name" \
  --endpoint-configuration '{"types":["PRIVATE"]}' \
  --security-policy "SecurityPolicy_TLS13_1_3_2025_09" \
  --endpoint-access-mode STRICT \
  --policy file://api-policy.json

Create a custom domain name with a security policy and STRICT endpoint access mode

You can also specify the security policy when creating a custom domain name. API Gateway applies the selected policy during TLS negotiation based on the SNI value the client provides.

aws apigateway create-domain-name \
  --domain-name api.example.com \
  --regional-certificate-arn arn:aws:acm:region:account-id:certificate/certificate-id \
  --endpoint-configuration '{"types":["REGIONAL"]}' \
  --security-policy SecurityPolicy_TLS13_1_3_2025_09 \
  --endpoint-access-mode STRICT

Updating existing REST API

If you are migrating an existing API, start by applying the enhanced security policy with BASIC mode. After confirming that your clients can connect with BASIC mode as expected, proceed to enable the STRICT mode.

1. Apply the new policy with BASIC mode

aws apigateway update-rest-api --rest-api-id abcd123 --patch-operations '[
    {
         "op": "replace",
         "path": "/securityPolicy",
         "value": "SecurityPolicy_TLS13_1_3_2025_09"
    },
    {
         "op": "replace",
         "path": "/endpointAccessMode",
         "value": "BASIC"
     }
]'

Verify your clients can consume the API as expected using access logs and performance metrics in Amazon CloudWatch.

2. Enable the STRICT mode after validation

aws apigateway update-rest-api --rest-api-id abcd123 --patch-operations '[
    {
        "op": "replace",
        "path": "/endpointAccessMode",
        "value": "STRICT"
     }
]'

Updating existing custom domain name

Custom domain names follow the same migration approach as REST APIs.

1. Apply the new policy with BASIC mode and validate clients can successfully connect.

aws apigateway update-domain-name --domain-name api.example.com --patch-operations '[
    {
        "op": "replace",
        "path": "/securityPolicy",
        "value": "SecurityPolicy_TLS13_1_3_2025_09"
    },
    {
        "op": "replace",
        "path": "/endpointAccessMode",
        "value": "BASIC"
     }
]'

2. Enable the STRICT mode after validation

aws apigateway update-domain-name --domain-name api.example.com --patch-operations '[
    {
        "op": "replace",
        "path": "/endpointAccessMode",
        "value": "STRICT"
     }
]'

After you update your REST API or custom domain configuration, redeploy your API so that stages receive the new settings. When you change a security policy, the update takes up to 15 minutes to complete. The API status appears as UPDATING while the change propagates and returns to AVAILABLE when complete. Your API remains fully functional throughout this process.

Rolling back endpoint access mode

If you notice clients failing to connect to your API after applying the STRICT mode, you can revert the endpoint access mode back to BASIC at any time. Below code snippet illustrates doing this for a REST API.

aws apigateway update-rest-api --rest-api-id abcd123 --patch-operations '[
    {
      "op": "replace",
      "path": "/endpointAccessMode",
      "value": "BASIC"
    }
  ]'

You can use the same approach to update a custom domain name.

Monitoring TLS usage and policy migrations

As you adopt enhanced security policies, it is important to understand how clients negotiate encrypted connections with your API. Monitoring helps you verify client readiness, identify legacy consumers that may require updates, and validate that STRICT endpoint access mode behaves as expected during rollout. Use the following API Gateway access logs variables to monitor protocol and cipher usage over time.

  • $context.tlsVersion – the negotiated TLS version
  • $context.cipherSuite – the cipher suite selected during the handshake

You can use these variables to confirm that:

  • Clients are using the expected minimum TLS version
  • BC-based ciphers are no longer used after you move to a hardened policy
  • PQC and FIPS-aligned policies are being exercised by the appropriate clients

Access logs are especially useful during migrations, where validating the actual client behavior is a prerequisite before enabling STRICT mode. For example, if you still observe live clients negotiating TLS 1.0 or TLS 1.2 CBC ciphers after applying a hardened policy in BASIC mode, you can identify the affected clients and plan remediation before switching to STRICT mode.

Future-proof security configurations

Some of the new policies combine TLS 1.3 with post-quantum cryptography (PQC) to help you prepare for a future where quantum-capable threat actors exist. With these policies you can start testing and adopting quantum-resistant algorithms without redesigning your API architecture.

As standards evolve and new cipher suites are introduced, API Gateway’s policy model provides you with a clear path for adding new variants while keeping your configuration simple and predictable.

Conclusion and next steps

Enhanced TLS security policies and endpoint access mode in the Amazon API Gateway gives you direct control over how clients establish secure connections to your APIs. You can choose the policies that match your compliance needs, such as PCI DSS, FIPS, Open Banking, PQC, and use STRICT mode to control how traffic reaches your endpoints and apply additional domain-level validations, further hardening security of your APIs

To get started:

  1. Review the list of available security policies in the API Gateway documentation.
  2. Identify which REST APIs and domains require stronger TLS controls.
  3. Apply an appropriate SecurityPolicy-* policy with BASIC mode.
  4. Validate client behavior using access logs and CloudWatch metrics.
  5. Move to STRICT mode when you are ready to enforce additional connection-level protection.

For more information about building Serverless architectures, see ServerlessLand.com

Practical steps to minimize key exposure using AWS Security Services

Post Syndicated from Jennifer Paz original https://aws.amazon.com/blogs/security/practical-steps-to-minimize-key-exposure-using-aws-security-services/

Exposed long-term credentials continue to be the top entry point used by threat actors in security incidents observed by the AWS Customer Incident Response Team (CIRT). The exposure and subsequent use of long-term credentials or access keys by threat actors poses security risks in cloud environments. Additionally, poor key rotation practices, sharing of access keys among multiple users, or failing to revoke unused credentials can leave systems exposed.

Using long-term credentials is strongly discouraged and presents an opportunity to migrate towards AWS Identity and Access Management (IAM) roles and federated access. While our recommended best practice is for customers to migrate away from long-term credentials, we recognize that this transition might not be immediately feasible for all organizations.

Building a comprehensive defense against unintended access to long-term credentials requires a strategic layered approach. This approach is intended to bridge the gap between ideal security practices and real-world operational constraints, providing actionable steps for teams managing legacy AWS workloads that require the use of long-term credentials.

In this post, you learn how to build your defense, starting with identifying existing risks and potential exposures through services such as Amazon CodeGuru Security and AWS IAM Access Analyzer, providing visibility into credential risks across the environment. This is then complemented by establishing strict boundaries through service control policies (SCPs) and data perimeters to control how and where credentials can be created and used. With these mechanisms in place, you can strengthen your position with network-level controls that help protect the infrastructure where access keys might be used, implementing services such as AWS WAF and Amazon Inspector to help protect against exploitation of vulnerabilities. Finally, you implement operational best practices such as automated secret rotation to maintain ongoing security hygiene and minimize the impact of potential compromise.

Detect current access keys and exposure

Audit current access keys

For comprehensive auditing, organizations should regularly generate credential reports to identify IAM user ownership of long-lived credentials and other relevant information such as the last time the key was rotated, last time it was used, last service used and last region used. These reports provide essential visibility into your credential landscape, enabling you to spot unused or potentially compromised credentials by focusing on access keys with stale activity, keys exceeding rotation policies, and unexpected usage patterns from unfamiliar regions.

Detect exposed access keys

A common source of credential compromise occurs through inadvertent commits to public repositories. When developers accidentally commit credentials to public repositories, these credentials can be harvested by automated scanning tools used by adversaries. Code scanning is a foundational step that helps catch these critical security issues early, before sensitive credentials can be accidentally committed to code repositories or deployed to production environments where they could be exploited.

You can use the secrets detection capability of CodeGuru Security to proactively identify exposed sensitive data in your codebase.

The tool integrates with AWS Secrets Manager, employing detection mechanisms to locate unencrypted secrets in your code, such as AWS secret access keys, embedded passwords, and database connection strings.

When CodeGuru Security discovers unprotected secrets during a scan, it creates a finding with recommended remediation to address the vulnerability.

AWS Trusted Advisor also contains an exposed access key check that checks popular code repositories for access keys that have been exposed to the public and for irregular Amazon Elastic Compute Cloud (Amazon EC2) usage that could be the result of a compromised access key.

Note that while these are valuable security tools, they cannot detect secrets or access keys stored in locations outside their scanning scope, such as local development machines or external systems. They should be used as part of a broader security strategy, not as the sole method for identifying and preventing credential exposure.

When addressing potentially compromised access keys, it is advised to immediately rotate the keys. See instructions on how to rotate access keys for IAM Users.

Detect unused access

Beyond identifying exposed credentials, detecting unused access keys helps minimize the attack surface. IAM Access Analyzer contains an unused access analyzer that looks for access permissions that are either overly generous or that have fallen into disuse, including unused IAM roles, access keys for IAM users, passwords for IAM users, and services and actions for active IAM roles and users. After reviewing the findings generated by an organization-wide or account-specific analyzer, you can remove or modify permissions that aren’t needed. By identifying and revoking unused credentials and access, you can limit the impact if credentials have been obtained by a threat actor.

By implementing these tools, you can gain insights into credential risks across your environment. The combined capabilities help surface embedded secrets, exposed access keys, and credentials requiring removal.

Preventive guardrails: Establish a data perimeter

Now that you’ve learned how to identify exposed or unused credentials, let’s explore how you can use SCPs and resource control policies (RCPs) to create a data perimeter and help make sure that only your trusted identities are accessing trusted resources from expected networks. Implementing preventive guardrails around your AWS environment is crucial for helping protect against unauthorized access and potential access key compromises. For more information on what a data perimeter is and how to establish one, see the Establishing a Data Perimeter on AWS blog post series.

The following SCP denies an IAM user’s credentials from being used outside of unexpected networks (corporate Classless Inter-Domain Routing (CIDR) or specific virtual private cloud (VPC)). This policy includes several actions in the NotAction element that would impact services access if not exempted. Examples of SCPs and RCPs can be found in the data-perimeter-policy-examples, which is the source of truth for newly revised policies. The following example has been updated to address the use case of user credentials being used outside of unexpected networks.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "EnforceNetworkPerimeterOnIAMUsers",
            "Effect": "Deny",
            "NotAction": [
                "es:ES*",
                "dax:GetItem",
                "dax:BatchGetItem",
                "dax:Query",
                "dax:Scan",
                "dax:PutItem",
                "dax:UpdateItem",
                "dax:DeleteItem",
                "dax:BatchWriteItem",
                "dax:ConditionCheckItem",
                "neptune-db:*",
                "kafka-cluster:*",
                "elasticfilesystem:client*",
                "rds-db:connect"
            ],
            "Resource": "*",
            "Condition": {
                "BoolIfExists": {
                    "aws:ViaAWSService": "false"
                },
                "NotIpAddressIfExists": {
                    "aws:SourceIp": [
                        "<my-corporate-cidr>"
                    ]
                },
                "StringNotEqualsIfExists": {
                    "aws:SourceVpc": [
                        "<my-vpc>"
                    ]
                },
                "ArnLike": {
                    "aws:PrincipalArn": [
                        "arn:aws:iam::*:user/*"
                    ]
                }
            }
        }
    ]

By implementing this network perimeter, you can reduce the risk of credential compromise leading to unauthorized access and data exposure. Threat actors attempting to use stolen credentials from a coffee shop or home network will be blocked, helping to limit the impact of unintended access to credentials.

To further increase your defense in depth, you can use RCPs to help protect your data, such as by using them to control which identities can access your resources. For example, you might want to allow identities in your organization to access resources in your organization. You might also want to prevent identities external to your organization from accessing your resources. You can enforce this control using RCPs. You can use RCPs to restrict the maximum available access to your resources and include which principals, both inside and outside your organization, can access your resources. SCPs can only impact the effective permissions for principals within your AWS organization.

By implementing the following RCP, you can help make sure that if long-lived credentials are accidentally exposed, unauthorized users from outside your organization will be blocked from using them to access your critical data and resources. The policy will deny Amazon Simple Storage Service (Amazon S3) actions unless requested from your corporate CIDR range (NotIpAddressIfExists with aws:SourceIp), or from your VPC (StringNotEqualsIfExists with aws:SourceVpc). See the list of AWS services that support RCPs. Examples of SCPs and RCPs can be found in this GitHub repository, which is the source of truth for newly revised policies. The following example has been updated to address the use case discussed in this post.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "EnforceNetworkPerimeter",
      "Effect": "Deny",
      "Principal": "*",
      "Action": [
		"s3:*",
		"sqs:*",
		"kms:*",
		"secretsmanager:*",
		"sts:AssumeRole",
		"sts:DecodeAuthorizationMessage",
		"sts:GetAccessKeyInfo",
		"sts:GetFederationToken",
		"sts:GetServiceBearerToken",
		"sts:GetSessionToken",
 		"sts:SetContext",
 		"aoss:*",
 		"ecr:*"
		],
      "Resource": "*",
      "Condition": {
        "NotIpAddressIfExists": {
          "aws:SourceIp": "<0.0.0.0/1>"
        },
        "StringNotEqualsIfExists": {
          "aws:SourceVpc": "<my-vpc>"
        },
        "BoolIfExists": {
          "aws:PrincipalIsAWSService": "false",
          "aws:ViaAWSService": "false"
        }
      }
	 }
    ]
  }

If you’re ready to begin migrating away from long-term credentials, using an SCP to deny access key creation and deny updates to existing keys helps enforce the use of more secure authentication methods like IAM roles and federated access. This policy denies principals from creating or updating an AWS access key.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Deny",
            "Action": [
                "iam:CreateAccessKey",
			 	"iam:UpdateAccessKey"
            ],
            "Resource": "*"
        }
    ]
}

In addition to establishing these data perimeter controls, let’s examine how network controls protect the runtime environments where access keys operate.

Network controls: Protecting the runtime environment for access keys

Beyond building a data perimeter and using SCPs and RCPs, protecting the compute and network infrastructure that uses these access keys is essential. The risk of credential exposure through compromised runtime environments makes infrastructure protection a critical component of access key security, because bad actors often target these environments to gain unauthorized access.

Security groups and network ACLs (NACLs)

Use network-level security protections that act as firewalls for varying levels, such as the instance level or the subnet level to help protect against unauthorized access.

  • Restricting critical ports, such as SSH (port 22) and RDP (port 3306), is essential because they’re prime targets for bad actors seeking unauthorized system access. Open administrative ports in your security groups can increase your attack surface and security risk. Using AWS Systems Manager Session Manager helps provide secure remote access without exposing inbound ports, alleviating the need for bastion hosts or SSH key management.
  • NACLs effectively block access at the subnet level by acting as stateless packet filters at subnet boundaries. Unlike security groups that protect individual instances, NACLs help secure entire subnets with explicit allow/deny rules for both inbound and outbound traffic. They create a critical perimeter defense layer that filters traffic before reaching your instances. When deployed as part of a defense-in-depth approach, NACLs provide subnet-level isolation between application tiers, block malicious traffic patterns at the network edge, and maintain protection even if other security layers are compromised, helping to facilitate comprehensive network security through multiple independent control points.
  • For enhanced network protection beyond NACLs, AWS Network Firewall enables enterprise-grade perimeter defense through comprehensive VPC protection. It combines intrusion prevention systems, domain filtering, deep packet inspection, and geographic IP controls, while automatically safeguarding your cloud environment against emerging threats using global threat intelligence gathered by Amazon. By using Network Firewall and AWS Transit Gateway integration, you can implement consistent security policies across your VPCs and Availability Zones with centralized management.
  • To automate and scale network security across your organization, AWS Firewall Manager provides centralized administration of both Network Firewall rules and security group policies. As your organization grows, Firewall Manager helps maintain security by automating the deployment of common security group policies, cleaning up unused groups, and remediating overly permissive rules across multiple accounts and organizational units.

Amazon Inspector

To help identify unintended network exposure at scale, consider using Amazon Inspector. Amazon Inspector continually scans AWS workloads for software vulnerabilities and unintended network exposure, helping you identify and remediate security vulnerabilities before they can be exploited.

Key capabilities include:

  • Package vulnerability: Package vulnerability findings identify software packages in your AWS environment that are exposed to Common Vulnerabilities and Exposures (CVEs). Bad actors can exploit these unpatched vulnerabilities to compromise the confidentiality, integrity, or availability of data, or to access other systems.
  • Code vulnerability: Code vulnerability findings identify lines in your AWS Lambda code that bad actors could exploit. Code vulnerabilities include injection flaws, data leaks, weak cryptography, or missing encryption in your code. It identifies policy violations and vulnerabilities based on internal detectors developed in collaboration with CodeGuru Security. For a list of possible detections, see the Amazon Q Detector Library.
  • Network reachability: Network reachability findings show whether your ports are reachable from the internet through an internet gateway (including instances behind Application Load Balancers or Classic Load Balancers), a VPC peering connection, or a VPN through a virtual gateway. These findings highlight network configurations that may be overly permissive, such as mismanaged security groups, NACLs or internet gateways, or that might allow for potentially malicious access. It can help identify open SSH ports on your instance security groups.

AWS WAF

Complementing your network security controls and vulnerability management, AWS WAF provides an additional layer of defense by filtering malicious web traffic that could lead to credential exposure.

AWS WAF offers several managed rule groups to protect against unauthorized access and common vulnerabilities:

  • AWS WAF Fraud Control account creation fraud prevention (ACFP) rule group: ACFP uses request tokens to gather information about the client browser and about the level of human interactivity in the creation of the account creation request. The rule group detects and manages bulk account creation attempts by aggregating requests by IP address and client session and aggregating by the provided account information such as the physical address and phone number. Additionally, the rule group detects and blocks the creation of new accounts using credentials that have been compromised, which helps protect the security posture of your application and of your new users.
  • AWS WAF Fraud Control account takeover prevention (ATP) rule group: To help prevent account takeovers that might lead to fraudulent activity, ATP gives you visibility and control over anomalous sign-in attempts and sign-in attempts that use stolen credentials. For Amazon CloudFront distributions, in addition to inspecting incoming sign-in requests, the ATP rule group inspects your application’s responses to sign-in attempts to track success and failure rates. ATP checks email and password combinations against its stolen credential database, which is updated regularly as new leaked credentials are found on the dark web.

Operational best practices

To complement these protective layers and maintain ongoing security posture, implement automated credential management through Secrets Manager to help facilitate proper rotation and lifecycle management of access keys throughout your environment. This automation reduces human error, helps facilitate timely credential updates and limits the exposure window if credentials are compromised.

It’s recommended to rotate keys at least every 90 days. Secrets Manager helps by automating the process of rotating secrets on a schedule, helping to make sure that credentials are regularly updated without manual intervention. It also centralizes the storage of secrets, reducing the likelihood of sharing access keys among multiple users. With Secrets Manager, you can configure automatic key rotation using a Lambda integration.

There is also an existing solution that can be deployed to implement automatic access key rotation at scale. This pattern helps you automatically rotate IAM access keys by using AWS CloudFormation templates, which are provided in the GitHub IAM key rotation repository.

If you’re unable to implement automatic rotation and need a quicker way to identify access keys that need to be rotated, AWS Trusted Advisor has a security check for IAM access key rotation that checks for active IAM access keys that haven’t been rotated in the last 90 days. You can use the security check to drill down on which access keys in your environment need to be rotated if you need to perform manual rotation.

Detect anomalous IAM activity

Finally, while proactive measures to secure your IAM infrastructure are crucial, it’s equally important to have robust detection and alerting mechanisms in place. No matter how diligent your efforts, there is still a possibility of unforeseen threats or unauthorized activities. That’s why a comprehensive defense-in-depth strategy should include the ability to quickly identify and respond to anomalous IAM-related events. Amazon GuardDuty combines machine learning and integrated threat intelligence to help protect AWS accounts, workloads, and data from threats.

GuardDuty Extended Threat Detection automatically correlates multiple events across different data sources to identify potential threats within AWS environments. When Extended Threat Detection detects suspicious sequences of activities, it generates comprehensive attack sequence findings. The system analyzes individual API activities as weak signals, which might not indicate risks independently, but when observed together in specific patterns can reveal potential security issues.

This capability is enabled by default when GuardDuty is activated in an AWS account, helping provide protection without additional configuration.

The specific attack sequence finding related to compromised credentials is AttackSequence:IAM/CompromisedCredentials which is marked as Critical severity. This finding informs you that GuardDuty detected a sequence of suspicious actions made by using AWS credentials that impacts one or more resources in your environment. Multiple suspicious and anomalous threat behaviors were observed by the same credentials, resulting in higher confidence that the credentials are being misused.

Conclusion

The security best practices outlined in this post provide a comprehensive, multi-layered approach to mitigate the risks associated with long-term credentials. By implementing proactive code scanning, automated key rotation, network-level controls, data perimeter restrictions, and threat detection, you can significantly reduce the attack surface and better protect your organization’s AWS resources until a full migration to temporary credentials is feasible.

While the recommendations provided in this post represent an ample set of controls to put organizations in a good security posture, there might be additional security measures that can be taken depending on the specific needs and risk profile of each environment. The key is to adopt a holistic, layered approach to credential management and protection. By doing so, you can bridge the gap until a complete transition to temporary credentials becomes possible.

Implementing these security measures can help reduce risks, but long-term credentials inherently carry security risks. Even with strict best practices and comprehensive security controls, the possibility of credential compromise cannot be removed completely. You should consider evaluating your organization’s security posture and prioritizing temporary credentials through IAM roles and federation whenever possible. If you have questions or need help, AWS is here to support you.

Jennifer Paz
Jennifer Paz

Jennifer is a Security Engineer with over a decade of experience, currently serving on the AWS Customer Incident Response Team (CIRT). Jennifer enjoys helping customers tackle security challenges and implementing complex solutions to help enhance their security posture. When not at work, Jennifer is an avid runner, pickleball enthusiast, traveler, and foodie, always on the hunt for new culinary adventures.
Samantha Tavares
Samantha Tavares

Samantha is an Incident Responder on the AWS Customer Incident Response Team. She’s passionate about helping customers protect their cloud environments. When she’s not diving into security challenges, she’s sweating at CrossFit, or planning her next travel adventure.

Accelerate investigations with AWS Security Incident Response AI-powered capabilities

Post Syndicated from Daniel Begimher original https://aws.amazon.com/blogs/security/accelerate-investigations-with-aws-security-incident-response-ai-powered-capabilities/

If you’ve ever spent hours manually digging through AWS CloudTrail logs, checking AWS Identity and Access Management (IAM) permissions, and piecing together the timeline of a security event, you understand the time investment required for incident investigation. Today, we’re excited to announce the addition of AI-powered investigation capabilities to AWS Security Incident Response that automate this evidence gathering and analysis work.

AWS Security Incident Response helps you prepare for, respond to, and recover from security events faster and more effectively. The service combines automated security finding monitoring and triage, containment, and now AI-powered investigation capabilities with 24/7 direct access to the AWS Customer Incident Response Team (CIRT).

While investigating a suspicious API call or unusual network activity, scoping and validation require querying multiple data sources, correlating timestamps, identifying related events, and building a complete picture of what happened. Security operations center (SOC) analysts devote a significant amount of time to each investigation, with roughly half of that effort spent manually gathering and piecing together evidence from various tools and complex logs. This manual effort can delay your analysis and response.

AWS is introducing an investigative agent to Security Incident Response, changing this paradigm and adding layers of efficiency. The investigative agent helps you reduce the time required to validate and respond to potential security events. When a case for a security concern is created, either by you or proactively by Security Incident Response, the investigative agent asks clarifying questions to make sure it understands the full context of the potential security event. It then automatically gathers evidence from CloudTrail events, IAM configurations, and Amazon Elastic Compute Cloud (Amazon EC2) instance details and even analyzes cost usage patterns. Within minutes, it correlates the evidence, identifies patterns, and presents you with a clear summary.

How it works in practice

Before diving into an example, let’s paint a clear picture of where the investigative agent lives, how it’s accessed, and its purpose and function. The investigative agent is built directly into Security Incident Response and is automatically available when you create a case. Its purpose is to act as your first responder—gathering evidence, correlating data across AWS services, and building a comprehensive timeline of events so you can quickly move from detection to recovery.

For example: you discover that AWS credentials for an IAM user in your account were exposed in a public GitHub repository. You need to understand what actions were taken with those credentials and properly scope the potential security event, including lateral movement and reconnaissance operations. You need to identify persistence mechanisms that might have been created and determine the appropriate containment steps. To get started, you create a case in the Security Incident Response console and describe the situation.

Here’s where the agent’s approach differs from traditional automation: it asks clarifying questions first. When were the credentials first exposed? What’s the IAM user name? Have you already rotated the credentials? Which AWS account is affected?

This interactive step gathers the appropriate details and metadata before it starts gathering evidence. Specifically, you’re not stuck with generic results—the investigation is tailored to your specific concern.

After the agent has what it needs, it investigates. It looks up CloudTrail events to see what API calls were made using the compromised credentials, pulls IAM user and role details to check what permissions were granted, identifies new IAM users or roles that were created, checks EC2 instance information if compute resources were launched, and analyzes cost and usage patterns for unusual resource consumption. Instead of you querying each AWS service, the agent orchestrates this automatically.

Within minutes, you get a summary, as shown in the following figure. The investigation summary includes a high-level summary and critical findings, which include the credential exposure pattern, observed activity and the timeframe, affected resources, and limiting factors.

This response was generated using AWS Generative AI capabilities. You are responsible for evaluating any recommendations in your specific context and implementing appropriate oversight and safeguards. Learn more about AWS Responsible AI requirements.

Note: The preceding example is representative output. Exact formatting will vary depending on findings.

The investigation summary includes various tabs for detailed information, such as technical findings with an events timeline, as shown in the following figure:

Figure 2 – Security event timeline

Figure 2 – Security event timeline

When seconds count, this transparency is paramount to a quick, high-fidelity, and accurate response—especially if you need to escalate to the AWS CIRT, a dedicated group of AWS security experts, or explain your findings to leadership, creating a single lens for stakeholders to view the incident.

When the investigation is complete, you have a high-resolution picture of what happened and can make informed decisions about containment, eradication, and recovery. For the preceding exposed credentials scenario, you might need to:

  • Delete the compromised access keys
  • Remove the newly created IAM role
  • Terminate the unauthorized EC2 instances
  • Review and revert associated IAM policy changes
  • Check for additional access keys created for other users.

When you engage with the CIRT, they can provide additional guidance on containment strategies based on the evidence the agent gathered.

What this means for your security operations

The leaked credentials scenario shows what the agent can do for a single incident. But the bigger impact is on how you operate day-to-day:

  • You spend less time on evidence collection. The investigative agent automates the most time-consuming part of investigations—gathering and correlating evidence from multiple sources. Instead of spending an hour on manual log analysis, you can spend most of that time on making containment decisions and preventing recurrence.
  • You can investigate in plain language. The investigative agent uses natural language processing (NLP), which you can use to describe what you’re investigating in plain language, such as unusual API calls from IP address X or data access from terminated employee’s credentials, and the agent translates that into the technical queries needed. You don’t need to be an expert in AWS log formats or know the exact syntax for querying CloudTrail.
  • You get a foundation for high-fidelity and accurate investigations. The investigative agent handles the initial investigation—gathering evidence, identifying patterns, and providing a comprehensive summary. If your case requires deeper analysis or you need guidance on complex scenarios, you can engage with the AWS CIRT, who can immediately build on the work the agent has already done, speeding up their response time. They see the same evidence and timeline, so they can focus on advanced threat analysis and containment strategies rather than starting from scratch.

Getting started

If you already have Security Incident Response enabled, the AI-powered investigation capabilities are available now—no additional configuration needed. Create your next security case and the agent will start working automatically.

If you’re new to Security Incident Response, here’s how to set it up:

  1. Enable Security Incident Response through your AWS Organizations management account. This takes a few minutes through the AWS Management Console and provides coverage across your accounts.
  2. Create a case. Describe what you’re investigating; you can do this through the Security Incident Response console or an API, or set up automatic case creation from Amazon GuardDuty or AWS Security Hub alerts.
  3. Review the analysis. The agent presents its findings through the Security Incident Response console, or you can access them through your existing ticketing systems such as Jira or ServiceNow.

The investigative agent uses the AWS Support service-linked role to gather information from your AWS resources. This role is automatically created when you set up your AWS account and provides the necessary access for Support tools to query CloudTrail events, IAM configurations, EC2 details, and cost data. Actions taken by the agent are logged in CloudTrail for full auditability.

The investigative agent is included at no additional cost with Security Incident Response, which now offers metered pricing with a free tier covering your first 10,000 findings ingested per month. Beyond that, findings are billed at rates that decrease with volume. With this consumption-based approach, you can scale your security incident response capabilities as your needs grow.

How it fits with existing tools

Security Incident Response cases can be created by customers or proactively by the service. The investigative agent is automatically triggered when a new case is created, and cases can be managed through the console, API, or Amazon EventBridge integrations.

You can use EventBridge to build automated workflows that route security events from GuardDuty, Security Hub, and Security Incident Response itself to create cases and initiate response plans, enabling end-to-end detection-to-investigation pipelines. Before the investigative agent begins its work, the service’s auto-triage system monitors and filters security findings from GuardDuty and third-party security tools through Security Hub. It uses customer-specific information, such as known IP addresses and IAM entities, to filter findings based on expected behavior, reducing alert volume while escalating alerts that require immediate attention. This means the investigative agent focuses on alerts that actually need investigation.

Conclusion

In this post, I showed you how the new investigative agent in AWS Security Incident Response automates evidence gathering and analysis, reducing the time required to investigate security events from hours to minutes. The agent asks clarifying questions to understand your specific concern, automatically queries multiple AWS data sources, correlates evidence, and presents you with a comprehensive timeline and summary while maintaining full transparency and auditability.

With the addition of the investigative agent, Security Incident Response customers now get the speed and efficiency of AI-powered automation, backed by the expertise and oversight of AWS security experts when needed.

The AI-powered investigation capabilities are available today in all commercial AWS Regions where Security Incident Response operates. To learn more about pricing and features, or to get started, visit the AWS Security Incident Response product page.

If you have feedback about this post, submit comments in the Comments section below.

Daniel Begimher

Daniel Begimher

Daniel is a Senior Security Engineer in Global Services Security, specializing in cloud security, application security, and incident response. He co-leads the Application Security focus area within the AWS Security and Compliance Technical Field Community, holds all AWS certifications, and authored Automated Security Helper (ASH), an open source code scanning tool.

Introducing Cluster insights: Unified monitoring dashboard for Amazon OpenSearch Service clusters

Post Syndicated from Siddhant Gupta original https://aws.amazon.com/blogs/big-data/introducing-cluster-insights-unified-monitoring-dashboard-for-amazon-opensearch-service-clusters/

Amazon OpenSearch Service clusters offer a wealth of operational metrics accessible through CloudWatch and the Amazon OpenSearch Service console to support effective performance monitoring and alert creation. Yet, pinpointing resiliency and performance challenges within your cluster can prove daunting. The process of identifying resource-intensive queries or understanding performance degradation trends can be time-consuming.

To address these challenges, we launched Cluster insights, which presents a unified dashboard delivering curated insights along with actionable mitigation steps. The dashboard displays detailed metrics at the node, index, and shard levels, coupled with a concise summary of security and resiliency best practices to uphold peak resiliency and availability.

This blog will guide you through setting up and using Cluster Insights, including key features and metrics. By the conclusion, you’ll understand how to use Cluster insights to recognize and address performance and resiliency issues within your OpenSearch Service clusters.

Getting Started with Cluster insights

Cluster insights is available at no additional cost to OpenSearch Service users running OpenSearch version 2.17 or later. Accessing Cluster insights requires admin-level permissions for your OpenSearch domain. Cluster insights is available only through the OpenSearch UI. OpenSearch UI offers support to multiple data sources, zero downtime upgrades for your dashboard experience, and curated workspaces for effective team collaborations. You first need to associate a data source (your clusters) with an OpenSearch UI application. Detailed steps are described in the user guide. Your OpenSearch UI console experience will look like following screenshots.

To access Cluster insights using the OpenSearch UI application:

  1. In the Amazon OpenSearch Service console, navigate to OpenSearch UI (Dashboards) and choose the Application URL to access your OpenSearch UI application.
  2. OpenSearch UI application, choose the settings icon at the left-bottom corner, then choose Data administration.
  3. On the Data administration overview page, or under Manage data in the left navigation, select Cluster insights.

Cluster insights overview

The Cluster insights – Overview acts as a landing page to show health and insights for all connected OpenSearch domains. It is organized into five sections:

  1. Current cluster status – Displays cluster health status (Green, Yellow, and Red) in a donut chart.
  2. Insights trend – Tracks issue patterns over the past 30 days, helping you identify emerging problems and track resolution progress. This trend analysis becomes particularly valuable when monitoring the impact of operational changes or troubleshooting recurring issues.
  3. Current open insights – Shows the count and severity breakdown of currently active insights across your clusters.
  4. OpenSearch service clusters – Lists all domains with their vital statistics such as health status, insights count, nodes, shards, and active queries.
  5. Top insights by severity – Prioritizes issues that need immediate attention. Each insight comes with a clear description and specific recommendations, transforming complex monitoring data into actionable tasks. This prioritized view helps teams can focus on critical issues first, whether they’re addressing shard size problems, disk space issues, or performance bottlenecks.

Together, these sections provide a comprehensive view of your OpenSearch Service infrastructure so you can assess cluster health, identify trends, and take action on critical issues from a single dashboard.

Cluster health

When you choose a specific cluster from the OpenSearch domains on the Cluster insights – Overview page, you will see cluster-specific details including health status, active insights, and performance metrics. The overview section displays cluster health along with essential metrics including count of shards, nodes, indices, and a total document size. You can also review the configuration best practices followed by domain across resiliency and security areas.

The lower section contains a table of actionable insights that presents a detailed view of current issues. This table mirrors the insights from the landing page but focuses specifically on issues affecting the selected cluster. You can observe high-severity issues such as low disk space and shard count problems, as well as medium-severity concerns that may impact cluster performance.

Each insight entry serves as an interactive element – selecting any issue reveals an in-depth analysis complete with root cause identification and specific remediation steps. The table includes important metadata such as generation timestamps, severity levels, recommendation counts, and current status, so users can prioritize and address issues effectively.

Insight details

Every insight offers detailed analysis and actionable recommendations. Take the Shard Count insight as an example: selecting it reveals a comprehensive breakdown of the issue. You’ll see that your OpenSearch cluster has breached the number of shards allowed on the nodes based on its JVM heap size, along with a detailed list of affected resources.

The detailed view includes a resource map that precisely identifies each impacted node and index, displaying critical information such as node IDs, shard counts, and the indices contributing to the issue.

The recommendations are organized into two levels: cluster-level recommendations address overall architecture improvements, such as scaling your cluster or adjusting global shard allocation settings. Index-level recommendations provide specific actions for individual indices—for example, you might see suggestions to move idle shards to UltraWarm storage. These are shards without any search or indexing operations for the last 10 days and are at least 5 days old, making them ideal candidates for warm storage to reduce the active shard count. All of this guidance is available directly within the Cluster insights interface, eliminating the need to switch between different tools or consoles.

Node, Index, Shard, and Query view

Next to cluster health, you can review Node, Index, Shard, and Query details for a specific cluster. These views present critical metrics such as resource (CPU, memory, disk) utilization, search and index latency.

Node view

The Node view tab provides a comprehensive view of individual node performance across your cluster. This table displays critical metrics for each node including heat score indicating overall node health, resource utilization (CPU, memory, disk), search and indexing latency and rates, along with quick links to view top N shards and queries running on each node.

This view helps you identify nodes experiencing high resource utilization or performance degradation. You can drill deeper into each node by clicking on the node ID to view detailed time-based metrics showing resource usage trends over time. Additionally, you can click the top N shards link to navigate directly to the Shard View, automatically filtered to show only the shards running on the selected node, allowing you to pinpoint which specific shards are contributing to performance issues.

Index view

The Index view tab shows performance metrics aggregated at the index level. For each index, you can monitor document count and storage size, search latency and rate, indexing latency and rate, and access top N queries affecting the index. This perspective is valuable for understanding which indices are driving cluster load and identifying optimization opportunities at the index configuration level.

Shard view

The Shard view tab offers the most granular view of cluster performance by displaying metrics for individual shards. Each row shows shard ID and its assigned node, index association and resource pressure metrics (CPU, memory), along with search and indexing latency per shard. This detailed view enables you to pinpoint specific shards causing performance issues, identify shard placement imbalances, and take targeted remediation actions.

Query view

The Query view on the Cluster insights page solves presents live dashboards that break down execution stats, CPU and memory usage, and completion progress for every query. This helps monitor which queries are driving the biggest resource consumption (the Top-N queries). With intuitive donut charts and scoreboards showing distribution by node, index, and user, this interface helps operators to quickly pinpoint performance bottlenecks and heavy workloads, supporting targeted optimization and confident scaling decisions.

Query insights

In addition to Cluster insights, you can also get Query insights to view the exact queries running and latencies across Expand, Query, and Fetch phases that provides valuable insights for search developers to further fine-tune their queries.

Conclusion

Cluster insights transforms OpenSearch Service cluster management from reactive troubleshooting to proactive optimization. By providing unified dashboards with heat score, and best practices across stability, resiliency, and security pillars, it offers visibility into your search infrastructure at the account level.

The actionable recommendations and step-by-step remediation guidance help users of all experience levels effectively resolve complex issues like shard imbalances and resource bottlenecks.

The integration with Query insights delivers real-time visibility into resource consumption patterns so that teams can identify and optimize performance-critical queries through detailed profiling and latency analysis.

For more information, see the AWS OpenSearch Service User Guide for additional details.


About the authors

Siddhant Gupta

Siddhant Gupta

Siddhant is a Senior Product Manager (Technical) at AWS, leading AI innovation for OpenSearch. He focuses on democratizing advanced AI capabilities, making them accessible and practical for customers regardless of their technical expertise. His work centers on seamlessly integrating cutting-edge AI technologies into scalable, user-friendly solutions.

Varunsrivathsa Venkatesha

Varunsrivathsa Venkatesha

Varunsrivathsa is a Software Development Manager at AWS, leading the Intelligent Domain Management team. He focuses on monitoring and recovery services for Amazon OpenSearch Service and on leveraging these services to provide a seamless domain management experience for customers.

Gagandeep Juneja

Gagandeep Juneja

Gagandeep is a senior software development engineer at AWS working on OpenSearch.

Jinhwan Hyon

Jinhwan Hyon

Jinhwan is a Specialist Solutions Architect at AWS focused on Amazon OpenSearch Service based on Seoul, South Korea. His interests center on data and analytics, with a passion for helping customers integrate AI into their data strategies. He’s particularly fascinated by generative AI and intelligent agents, exploring how these technologies can revolutionize decision-making and solve complex business challenges.

The Agentic AI Security Scoping Matrix: A framework for securing autonomous AI systems

Post Syndicated from Aaron Brown original https://aws.amazon.com/blogs/security/the-agentic-ai-security-scoping-matrix-a-framework-for-securing-autonomous-ai-systems/

As generative AI became mainstream, Amazon Web Services (AWS) launched the Generative AI Security Scoping Matrix to help organizations understand and address the unique security challenges of foundation model (FM)-based applications. This framework has been adopted not only by AWS customers across the globe, but also widely referenced by organizations such as OWASP, CoSAI, and other industry standards bodies, partners, systems integrators (SIs), analysts, auditors, and more. Now, as long-running, function-calling agentic AI systems emerge with capabilities for autonomous decision-making, we’re creating an additional framework to address an entirely new set of security challenges.

Agentic AI systems can autonomously execute multi-step tasks, make decisions, and interact with infrastructure and data. This is a paradigm shift, and organizations must adapt to it. Unlike traditional FMs that operate in stateless request-response patterns, agentic AI systems introduce autonomous capabilities, persistent memory, tool orchestration, identity and agency challenges, and external system integration, expanding the risks that organizations must address.

Working with customers deploying these systems, we’ve observed that traditional AI security frameworks don’t always extend into the agentic space. The autonomous nature of agentic systems requires fundamentally different security approaches. To address this gap, we’ve developed the Agentic AI Security Scoping Matrix, a mental model and framework that categorizes four distinct agentic architectures based on connectivity and autonomy levels, mapping critical security controls across each.

Understanding the agentic paradigm shift

FM-powered applications operate in a now well-understood, predictable pattern even though the responses that an FM produces are non-deterministic and stateless. These applications, in their most basic form receive a prompt or instruction, generate a response, then terminate the session. Security and safety controls focus on basic measures such as input validation, output filtering, and content moderation guardrails, while governance focuses on the overall risk profiles and the resilience of models. This model works because security failures have limited scope: a compromised interaction affects only that specific request and response, without persisting or propagating to other systems or users.

Agentic AI systems fundamentally change this security model through several key capabilities:

Autonomous execution and agency: Agents initiate actions based on goals and environmental triggers that might, or might not, require human prompts or approval. This creates risks of unauthorized actions, runaway processes, and decisions that exceed intended boundaries when agents misinterpret objectives or operate on compromised instructions.

When AI agents are given instructions or permissions to act based on the data, parameters, instructions, and responses given to them, the boundaries of independence or autonomy they are permitted to act within are important to define. In discussing agentic AI systems, it’s important to clarify the distinction between agency and autonomy, because these related but different concepts inform our security approach.

Agency refers to the scope of actions an AI system is permitted and enabled to take within the operating environment, and how much a human bounds an agent’s actions or capabilities. This includes what systems it can interact with, what operations it can perform, and what resources it can modify. Agency is fundamentally about capabilities and permissions—what the system is allowed to do within its operational environment. For example, an AI agent with no agency would be guided by human-defined workflow, process, tools, or orchestration compared to an AI agent with full agency that can self-determine how to accomplish a human-defined goal.

Autonomy, in contrast, refers to the degree of independent decision-making and action the system can take without human intervention. This includes when it operates, how it chooses between available actions, and whether it requires human approval for execution. Autonomy is about independence in decision-making and execution—how freely the system can act within its granted agency. For example, an AI agent might have high agency (able to perform many actions) but low autonomy (requiring human approval for each action), or vice versa.

Understanding this distinction is crucial for implementing appropriate security controls. Agency requires boundaries and permission systems, while autonomy requires oversight mechanisms and behavioral controls. Both dimensions must be carefully managed to create secure agentic AI systems.

It’s important to determine how much agency and autonomy you want to permit and grant your AI agents to act within. After you have determined the appropriate level that any given agent should operate within, you can then evaluate the appropriate security controls to put in place to restrict the agency to a permissible risk tolerance for your agentic-based application and your organization.

Persistent memory: Agents often benefit from maintaining context and learned behaviors across sessions, building knowledge bases that inform future decisions in the form of short- and long-term memory. This data persistence introduces additional data protection requirements and can add new risk vectors such as memory poisoning attacks where adversaries inject false information that corrupts decision-making across multiple interactions and users.

Tool orchestration: Agents directly integrate via functions with connections to databases, APIs, services, and potentially other agents or orchestration components to execute complex tasks autonomously depending on the tool abstraction level. This expanded attack surface creates risks of cascading compromises where a single agent breach can propagate through connected systems, multi-agent workflows, and downstream services and data stores.

External connectivity: Agents operate across network boundaries, accessing internet resources, third-party APIs, and enterprise systems. Like traditional non-agentic systems, expanded connectivity can help unlock new business value, but this access should be designed with security controls that limit risks such as data exfiltration, lateral movement, and external manipulation. Threat modeling your agentic AI applications should be a high priority and can help directly align security controls that assist your implementation of zero-trust principles into your strategy.

Self-directed behavior: Advanced agents can initiate activities based on environmental monitoring, scheduling, or learned patterns without human instantiation or review, depending on configuration. This self-direction introduces risks of uncontrolled operations, explainability, and auditability, and makes it difficult to maintain predictable security boundaries.

These capabilities transform security from a boundary problem to a continuous monitoring and control challenge. A compromised agent doesn’t just leak information—it could autonomously execute unauthorized transactions, modify critical infrastructure, or operate maliciously for extended periods without detection.

The Agentic AI Security Scoping Matrix

Working with customers and the community, we’ve identified four architectural scopes that represent the evolution of agentic AI systems based on two critical dimensions: level of human oversight compared with autonomy and the level of agency the AI system is permitted to act within. Each scope introduces new capabilities—and corresponding security requirements—that organizations must prioritize when addressing agentic AI risk. Figure 1 shows the Agentic AI Security Scoping Matrix.

Figure 1 - The Agentic AI Security Scoping Matrix

Figure 1 – The Agentic AI Security Scoping Matrix

Scope 1: No agency

In this most basic scope, systems operate with human-initiated processes and no autonomous or even human-approved change capabilities through the agent itself. The agents are, essentially, read-only. These systems follow predefined execution paths and operate under strict human-triggered workflows, which are usually predefined and follow discrete steps, but could be augmented with non-deterministic outputs from an FM. Security focuses primarily on process integrity and boundary enforcement, helping operations remain within predetermined limits and agents are highly controlled and prohibited from change execution and unbounded actions.

Key characteristics:

  • Agents can’t directly execute change in the environment
  • Fixed step-by-step execution following predetermined paths
  • Generative AI components process data within individual workflow nodes
  • Conditional branching only where explicitly designed into the workflow
  • No dynamic planning or autonomous goal-seeking behavior
  • State persistence limited to workflow execution context
  • Tool access restricted to specific predefined workflow steps

Security focus: Protecting data integrity within the environment and restricting agents to not exceed their boundaries, especially limits around environment and data modification. Primary concerns include securing state transitions between steps, validating data passed between workflow nodes, and preventing AI components from modifying the orchestration logic or escaping their designated boundaries within the workflow.

Example: We will use a very simplistic example, across all four scopes, of a use case for an agent that is designed to help you create calendar invites. Let’s say you need to book a meeting with another colleague. In Scope 1, you might have an agent that you instantiate through a workflow or prompt to look at your calendar and your colleague’s calendar for available meeting times. In this case, you initiate the request, and the agent executes a contextual search using a Model Context Protocol (MCP) server connected to your enterprise calendaring application. The agent is only allowed to look at available times, analyze the best times to meet, and provide a response back, which a human can then use to manually set up a meeting. In this example, the human defines specific workflows and orchestrations (no agency) and reviews and approves the actions taken (no autonomous change).

Scope 2: Prescribed agency

Moving up in agency and risk, Scope 2 systems also are instantiated by a human, but now have the potential to perform actions—limited agency—that could change the environment. However, all actions taken by an agent require explicit human approval for all actions of consequence—commonly referred to as human in the loop or HITL. These systems can gather information, analyze data, and prepare recommendations, but cannot execute actions that modify external systems or access sensitive resources without human authorization. Agents can also request human input to clarify ambiguities, provide missing context, or optimize their approach before presenting recommendations.

Key characteristics:

  • Agents can execute change in the environment with human review and approval
  • Real-time human oversight with approval workflows
  • Bidirectional human interaction—agents can query humans for context
  • Limited autonomous actions restricted to read-only operations (such as, querying data, running analysis jobs, and so on)
  • Agent-initiated requests for clarification or additional information
  • Audit trails of all human approval decisions and context exchanges

Security focus: Implementing robust approval workflows and preventing agents from bypassing human authorization controls. Key concerns include preventing privilege escalation, enforcing appropriate identity contexts, securing the approval process itself, validating human-provided context to prevent injection attacks, and maintaining visibility into all agent recommendations and their rationale.

Example: In our calendaring example, a Scope 2 agentic system is instantiated by a human. The agent then looks up the stakeholders’ calendar availability, does its analysis, returns a recommendation for a meeting time to the user, and asks the user if they want the agent to send the invitation out on their behalf. The user looks at the response and recommendation of the agent, validates that it meets their requirements, and then acknowledges and approves the agent’s request to modify the calendars and send the invitation. In this example, the human orchestrates a structured workflow, but the agent now can instantiate human reviewed change through bounded actions (limited agency and limited autonomy).

Scope 3: Supervised agency

In Scope 3, we expand the agency to allow for a greater sense of agentic autonomy—high agency—in execution. These are AI systems that execute complex autonomous tasks that are initiated by humans (or at least from an upstream human-managed workflow), with the ability to make decisions and take actions to connected systems without further approval or HITL mechanisms. Humans define the objectives and trigger execution, but agents operate independently to achieve goals through dynamic planning and tool usage. During execution, agents can request human guidance to optimize trajectory or handle edge cases, though they can continue operating without it.

Key characteristics:

  • Agents can execute change in the environment, with no (or optional) human interaction or review
  • Human-triggered execution with autonomous task completion
  • Dynamic planning and decision-making during execution
  • Optional human intervention points for trajectory optimization
  • Human ability to adjust parameters or provide context mid-execution
  • Direct access to external APIs and systems for task completion
  • Persistent memory across extended execution sessions
  • Autonomous tool selection and orchestration within defined boundaries

Security focus: Implementing comprehensive monitoring of agent actions during autonomous execution phases and establishing clear agency boundaries for agent operations—the bounds you’re willing to let the agents operate within, and actions that would be out of bounds and must be prevented. Critical concerns include securing the human intervention channel to prevent unauthorized modifications, preventing scope creep during task execution, implementing trusted identity propagation constructs, monitoring for behavioral anomalies, and validating that agents remain aligned with original human intent throughout extended operations even when trajectory adjustments are made.

Example: In our calendaring example, a Scope 3 agentic system can still be instantiated by a human. The agent then looks up the stakeholders’ calendar availability, does its analysis, and returns a recommendation for a meeting time to the user; however, it’s within the agent’s bounds to act upon its own recommendation on behalf of the user to automatically book the best available slot. The user is not prompted or expected to give the agent permission to do so prior to its actions. The result is that all stakeholders have a calendar entry added to their calendar in the context of the calling human user. In this example, the human defines an outcome but with more freedom for the agent to determine how to achieve that goal, and the agent now can take autonomous action without human review (high agency and high autonomy).

Scope 4: Full agency

Scope 4 includes fully autonomous AI systems that can initiate their own activities based on environmental monitoring, learned patterns, or predefined conditions, and execute complex tasks without human intervention. These systems represent the highest level of AI agency, operating continuously and making independent decisions about when and how to act. It’s key to note that AI systems within Scope 4 could have full agency when executing within their designed bounds; therefore, it’s critical that humans maintain supervisory oversight with the ability to provide strategic guidance, course corrections, or interventions when needed. Continuous compliance, auditing, and full-lifecycle management mechanisms, both human and automated reviews, which could also be aided by AI, are critical to successfully securing and governing Scope 4 agentic AI systems while limiting risk.

Key characteristics:

  • Self-directed activity initiation based on environmental triggers
  • Continuous operation with minimal human oversight or HITL processes during execution
  • Human ability to inject strategic guidance without disrupting operations
  • High to full degrees of autonomy in goal setting, planning, and execution
  • Dynamic interaction with multiple external systems and agents
  • Capability for recursive self-improvement and capability expansion

Security focus: Implementing advanced guardrails for behavioral monitoring, anomaly detection, scope-based tool access controls, and fail-safe mechanisms to prevent runaway operations. Primary concerns include maintaining alignment with organizational objectives, securing human intervention channels against adversarial manipulation, preventing unauthorized capability expansion, preventing human oversight mechanisms from being disabled by the agent, and enabling graceful degradation when agents encounter unexpected situations.

Example: Let’s look at how we might deploy our AI calendaring example in Scope 4. Let’s say you have implemented a generative AI meeting summarizer. This agent is automatically enabled when you host a web conference. At the conclusion of the meeting, the calendaring agent sees a new meeting occurred from the meeting summarizer agent. It looks at the action items that were summarized and determines that six people agreed to a whiteboard session on Friday. The calendaring agent might either have a statically defined API configuration or leverage dynamic discovery on MCP servers to help with calendaring. It then finds availability for the six identified resources and books the best available slot. It then uses the appropriate identity context of the user who is asking for the meeting to book the meeting autonomously. At no point does a user directly instantiate the request for calendaring; it is fully automated and driven off environment changes that the agent is instructed to look for (full agency and full autonomy).

Scope comparison across the scopes

In the context of the security scoping matrix, let’s compare how autonomy and agency characteristics shift depending on the scope:

Table 1 – Scope impacts on agency and autonomy levels

Critical security dimensions

Scope

Agency level

Agency characteristics

Autonomy level

Autonomy characteristics

Scope 1: No agency

None

  • Read-only operations
  • Fixed workflow paths

None

  • Human-initiated only
  • Predefined execution steps

Scope 2: Prescribed agency

Limited

  • Can modify systems
  • Access to multiple tools

Limited

  • Requires human approval for actions
  • HITL for all changes

Scope 3: Supervised agency

High

  • Can modify multiple systems
  • Dynamic tool selection

High

  • Autonomous execution after human initiation
  • Optional human guidance

Scope 4: Full agency

Full

  • Comprehensive system access
  • Multi-system orchestration
  • Self-adaptive

Full

  • Self-initiated actions
  • Continuous autonomous operation
  • Strategic human oversight

Each architectural scope requires specific security controls and considerations across six critical dimensions. Table 2 illustrates how security requirements escalate with increasing agency and autonomy:

Security dimension

Scope 1: No agency

Scope 2: Prescribed agency

Scope 3: Supervised agency

Scope 4: Full agency

Identity context (authN and authZ)

  • User authentication
  • Service authentication
  • Limited system permissions (read-only)
  • Limited system access (only necessary, known systems needed for the workflow)
  • User authentication
  • Service authentication
  • Human identity verification for approvals
  • User authentication
  • Service authentication
  • Agent authentication
  • Identity delegation for autonomous actions
  • Dynamic identity lifecycle
  • Federated authentication
  • Continuous identity verification
  • Agent identity attestation

Data, memory, and state protection

  • Local resource permissions
  • File system access controls
  • Role-based access control
  • Human approval workflows
  • Read-mostly permissions for agents
  • Context-aware authorization
  • Just-in-time privilege elevation
  • Dynamic permission boundaries
  • Behavioral authorization
  • Adaptive access controls
  • Continuous authorization validation

Audit and logging

  • Local activity logs
  • Change tracking
  • Integrity monitoring
  • Policy enforcement
  • Human decision audit trails
  • Agent recommendation logging
  • Approval process tracking
  • Comprehensive action logging
  • Reasoning chain capture
  • Extended session tracking
  • Continuous behavioral logging
  • Pattern analysis
  • Predictive monitoring
  • Automated incident correlation

Agent and FM controls

  • Process isolation
  • Input/output validations
  • Guardrails
  • Approval gateway enforcement
  • Extended session monitoring
  • Container isolation
  • Long-running process management
  • Tool invocation sandboxing
  • Behavioral analysis
  • Anomaly detection
  • Automated containment
  • Self-healing security

Agency perimeters and policies

  • Fixed execution boundaries
  • Predefined action limits
  • Static resource quotas
  • Hard-coded constraints
  • Approval-based boundary modification
  • Human-validated constraint changes
  • Time-bound elevated access
  • Multi-step validation
  • Dynamic boundary adjustment
  • Runtime constraint evaluation
  • Resource scaling limits
  • Automated safety checks
  • Self-adjusting boundaries
  • Context-aware constraints
  • Cross-system resource management
  • Autonomous limit adaptation

Orchestration

  • Simple workflow orchestration
  • Fixed execution paths
  • Single or limited system integration points
  • Multi-step workflow orchestration
  • Approval-gated tool access
  • Human-validated tool chains
  • Dynamic tool orchestration
  • Parallel execution paths
  • Cross-system integration
  • Autonomous multi-agent orchestration
  • Cross-session learning
  • Dynamic service discovery

Table 2 — Critical security dimensions per scope

Security implementation by scope

Now that we’ve outlined each of the scopes and the associated levels of agency and autonomy, let’s discuss some primary security challenges per scope and key considerations that should be taken to address the associated risks.

Scope 1: No agency
Primary security challenges: Protecting workflow integrity, preventing prompt injection from breaking predetermined flows, and maintaining isolation between workflow executions.

Implementation considerations:

  • Comprehensive monitoring with anomaly detection
  • Strict data validation and integrity checking
  • Input validation at each workflow step boundary
  • Immutable workflow definitions with version control
  • State encryption and validation between workflow nodes
  • Monitoring for attempts to escape workflow boundaries
  • Segregation between different workflow executions
  • Fixed timeout and resource limits per workflow step
  • Audit trails showing actual compared to expected execution paths

Scope 2: Prescribed agency
Primary security challenges: Securing approval workflows, preventing human authorization bypass, and maintaining oversight effectiveness.

Implementation considerations:

  • Multi-factor authentication for all human approvers
  • Cryptographically signed approval decisions
  • Securing bidirectional human-agent communication channels
  • Time-bounded approval tokens with automatic expiration
  • Comprehensive logging of all approval interactions
  • Regular training for human approvers on agent capabilities and risks

Scope 3: Supervised agency
Primary security challenges: Maintaining control during autonomous execution, scope management, explainability and auditability, and behavioral monitoring.

Implementation considerations:

  • Clear execution boundaries defined at initiation
  • Real-time monitoring of agent actions during execution
  • Automated kill switches for runaway processes
  • Non-blocking intervention mechanisms
  • Behavioral baselines for normal agent operations
  • Regular validation of agent alignment with original objectives

Scope 4: Full agency
Primary security challenges: Continuous behavioral validation, enforcing agency boundaries, preventing capability drift, and maintaining organizational alignment.

Implementation considerations:

  • Advanced AI safety techniques including reward modeling
  • Continuous monitoring with machine learning-based anomaly detection
  • Automated response systems for behavioral deviations
  • Regular alignment validation through systematic testing
  • Tamper-proof human override mechanisms
  • Failsafe mechanisms that can halt operations when confidence drops

Key architectural patterns

Successful agentic deployments share common patterns that balance autonomy with control.

Progressive autonomy deployment: Start with Scope 1 or 2 implementations and gradually advance through the scopes as organizational confidence and security capabilities mature. This approach minimizes risk while building operational experience. Be cautious and selective when analyzing use cases and bounding controls for Scope 4 implementations and review your ability to address risks at the lower scopes and how risks increase as you move further up the levels.

Layered security architecture: Implement defense-in-depth with security controls at multiple levels—network, application, agent, and data layers—to safeguard that compromise at one level doesn’t lead to complete system failure. Although the combination of these controls is what enables a high security bar, be sure to spend considerable efforts on making sure that identity and authorization concerns are addressed—for both machines and humans. This helps prevent issues such as the confused deputy problem—when a human or service with lesser permissions is able to elevate permissions through agents that might themselves have more entitlements and privileges.

Continuous validation loops: Establish automated systems that continuously verify agent behavior against expected patterns, and that have escalation procedures for when deviations are detected. Auditability and explainability are key requirements to confirm that agents are performing within the bounds intended and to help you determine control effectiveness, adjust parameters, and validate your orchestration workflows.

Human oversight integration: Even in highly autonomous systems, maintain meaningful human oversight through strategic checkpoints, behavioral reporting, and manual override capabilities. It might be reasonable to assume that human oversight reduces when moving from Scope 1 to Scope 4 agency, but the truth is that it simply shifts focus. For example, the human requirement to instantiate, review, and approve certain agentic actions is higher in Scopes 1 and 2 and lower in Scopes 3 and 4; however, the human requirement to audit, assess, validate, and implement more complex security and operational controls is much higher in Scopes 4 and 3 than they are in Scopes 2 and 1.

Graceful degradation: Design systems to automatically reduce autonomy levels when security events are detected, allowing operations to continue safely while human operators investigate. If your agents start to act in ways that go beyond the intended bounds of their design, anomalous behavior is detected, or they begin to perform actions deemed particularly risky or sensitive to your business, then consider having detective controls that will automatically inject tighter restrictions such as requiring more HITL or reducing the actions an agent can take. You might do this as incremental degradation or, you might choose to disable the agent if it’s acting in ways that negatively impact the environment. These agentic safety mechanisms that can implement additional restrictions or even disable an agent should be considered when building or deploying agents.

Conclusion

The Agentic AI Security Scoping Matrix provides a structured mental model and framework for understanding and addressing the security challenges of autonomous agentic AI systems across four distinct scopes. By accurately assessing your current scope and implementing appropriate controls across all six security dimensions, organizations can confidently deploy agentic AI while managing the landscape of associated risks.

The progression from basic and highly constrained agents to fully autonomous and even self-directing agents represents a fundamental shift in how we approach AI security. Each scope requires specific security capabilities, and organizations must build these capabilities systematically to support their agentic ambitions safely.

Next steps

To implement the Agentic AI Security Scoping Matrix in your organization:

  1. Assess your current agentic use cases and maturity against the four scopes to understand your security requirements and associated risks. Integrate it into your procurement and SDLC processes.
  2. Identify capability gaps across the six security dimensions for your target scope.
  3. Develop a progressive deployment strategy that builds security capabilities as you advance through scopes.
  4. Implement continuous monitoring and behavioral analysis appropriate for your scope level.
  5. Establish governance processes for scope progression and security validation.
  6. Train your teams on the unique security challenges of each scope.

You can find additional information on the Agentic AI Security Scoping matrix here, along with additional information on AI security topics. For additional resources on securing AI workloads, see the AI for security and security for AI: Navigating Opportunities and Challenges whitepaper and explore purpose-built platforms designed for the unique challenges of agentic AI.
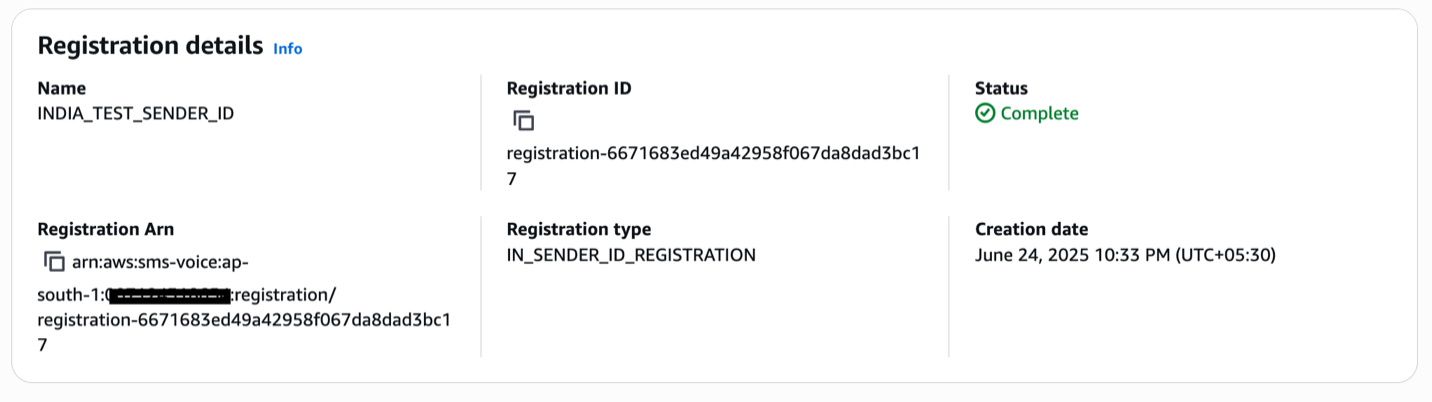
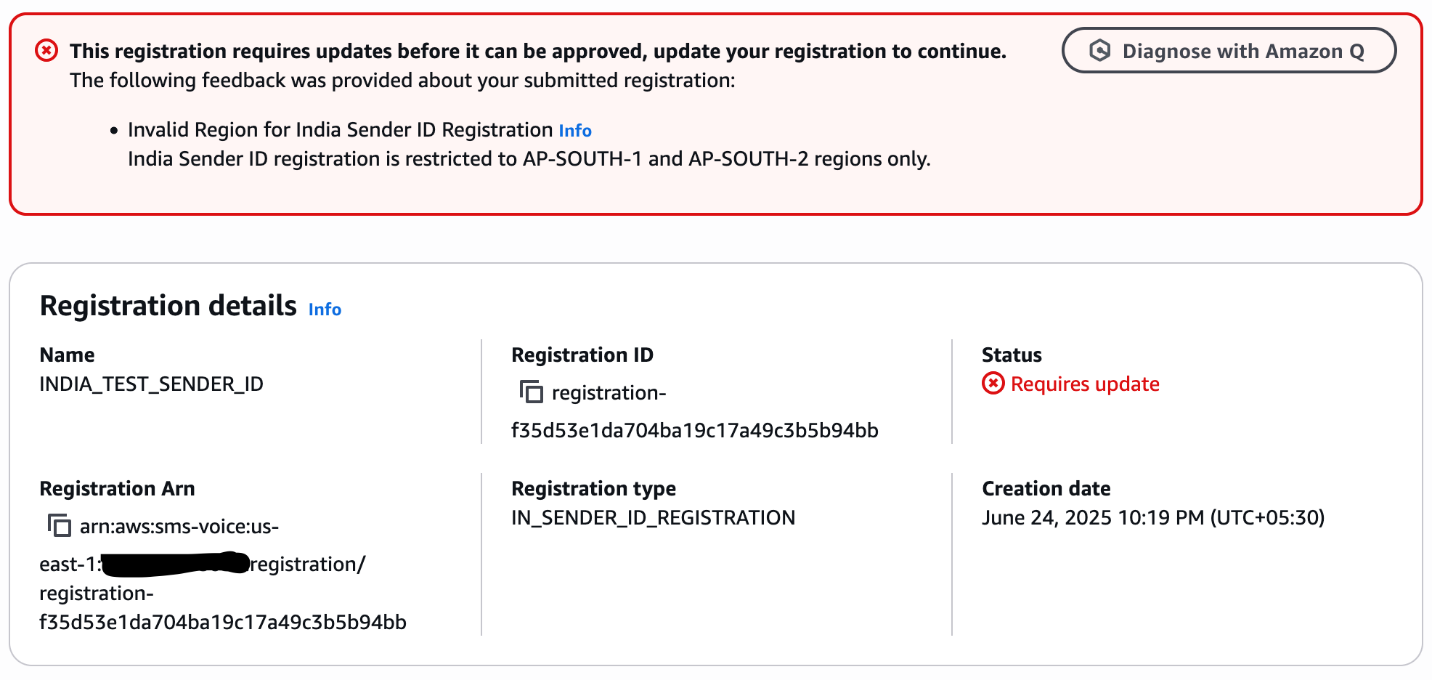
If you have feedback about this post, submit comments in the Comments section below.
Aaron Brown

Aaron Brown

Aaron Brown is a Senior AI Security Architect at AWS with over 8+ years of experience designing, building and shipping AI solutions in the offensive and defensive security domains.

Matt Saner

Matt Saner

Matt Saner is a global security leader helping customers unblock and accelerate complex security challenges. He plays a key role in the development of security standards for AI, including serving on the project governing board and executive steering committee for the Coalition for Secure AI (CoSAI) and as a distinguished review board member for OWASP’s GenAI and Agentic AI security projects.