Multimodal search enables both text and image search capabilities, transforming how users access data through search applications. Consider building an online fashion retail store: you can enhance the users’ search experience with a visually appealing application that customers can use to not only search using text but they can also upload an image depicting a desired style and use the uploaded image alongside the input text in order to find the most relevant items for each user. Multimodal search provides more flexibility in deciding how to find the most relevant information for your search.
To enable multimodal search across text, images, and combinations of the two, you generate embeddings for both text-based image metadata and the image itself. Text embeddings capture document semantics, while image embeddings capture visual attributes that help you build rich image search applications.
Amazon Titan Multimodal Embeddings G1 is a multimodal embedding model that generates embeddings to facilitate multimodal search. These embeddings are stored and managed efficiently using specialized vector stores such as Amazon OpenSearch Service, which is designed to store and retrieve large volumes of high-dimensional vectors alongside structured and unstructured data. By using this technology, you can build rich search applications that seamlessly integrate text and visual information.
Amazon OpenSearch Service and Amazon OpenSearch Serverless support the vector engine, which you can use to store and run vector searches. In addition, OpenSearch Service supports neural search, which provides out-of-the-box machine learning (ML) connectors. These ML connectors enable OpenSearch Service to seamlessly integrate with embedding models and large language models (LLMs) hosted on Amazon Bedrock, Amazon SageMaker, and other remote ML platforms such as OpenAI and Cohere. When you use the neural plugin’s connectors, you don’t need to build additional pipelines external to OpenSearch Service to interact with these models during indexing and searching.
This blog post provides a step-by-step guide for building a multimodal search solution using OpenSearch Service. You will use ML connectors to integrate OpenSearch Service with the Amazon Bedrock Titan Multimodal Embeddings model to infer embeddings for your multimodal documents and queries. This post illustrates the process by showing you how to ingest a retail dataset containing both product images and product descriptions into your OpenSearch Service domain and then perform a multimodal search by using vector embeddings generated by the Titan multimodal model. The code used in this tutorial is open source and available on GitHub for you to access and explore.
Multimodal search solution architecture
We will provide the steps required to set up multimodal search using OpenSearch Service. The following image depicts the solution architecture.
OpenSearch Service calls the Amazon Bedrock Titan Multimodal Embeddings model to generate multimodal vector embeddings for both the product description and image.
Through an OpenSearch Service client, you pass a search query.
OpenSearch Service calls the Amazon Bedrock Titan Multimodal Embeddings model to generate vector embedding for the search query.
OpenSearch runs the neural search and returns the search results to the client.
Let’s look at steps 1, 2, and 4 in more detail.
Step 1: Ingestion of the data into OpenSearch
This step involves the following OpenSearch Service features:
Ingest pipelines – An ingest pipeline is a sequence of processors that are applied to documents as they’re ingested into an index. Here you use a text_image_embedding processor to generate combined vector embeddings for the image and image description.
k-NN index – The k-NN index introduces a custom data type, knn_vector, which allows users to ingest vectors into an OpenSearch index and perform different kinds of k-NN searches. You use the k-NN index to store both the general field data types, such as text, numeric, etc., and specialized field data types, such as knn_vector.
Steps 2 and 4: OpenSearch calls the Amazon Bedrock Titan model
OpenSearch Service uses the Amazon Bedrock connector to generate embeddings for the data. When you send the image and text as part of your indexing and search requests, OpenSearch uses this connector to exchange the inputs with the equivalent embeddings from the Amazon Bedrock Titan model. The highlighted blue box in the architecture diagram depicts the integration of OpenSearch with Amazon Bedrock using this ML-connector feature. This direct integration eliminates the need for an additional component (for example, AWS Lambda) to facilitate the exchange between the two services.
Solution overview
In this post, you will build and run multimodal search using a sample retail dataset. You will use the same multimodal generated embeddings and experiment by running text search only, image search only and both text and image search in OpenSearch Service.
Prerequisites
Create an OpenSearch Service domain. For instructions, see Creating and managing Amazon OpenSearch Service domains. Make sure the following settings are applied when you create the domain, while leaving other settings as default.
OpenSearch version is 2.13
The domain has public access
Fine-grained access control is enabled
A master user is created
Set up a Python client to interact with the OpenSearch Service domain, preferably on a Jupyter Notebook interface.
Note that you need to refer to the Jupyter Notebook in the GitHub repository to run the following steps using Python code in your client environment. The following sections provide the sample blocks of code that contain only the HTTP request path and the request payload to be passed to OpenSearch Service at every step.
Data overview and preparation
You will be using a retail dataset that contains 2,465 retail product samples that belong to different categories such as accessories, home decor, apparel, housewares, books, and instruments. Each product contains metadata including the ID, current stock, name, category, style, description, price, image URL, and gender affinity of the product. You will be using only the product image and product description fields in the solution.
A sample product image and product description from the dataset are shown in the following image:
Figure 2: Sample product image and description
In addition to the original product image, the textual description of the image provides additional metadata for the product, such as color, type, style, suitability, and so on. For more information about the dataset, visit the retail demo store on GitHub.
Step 1: Create the OpenSearch-Amazon Bedrock ML connector
The OpenSearch Service console provides a streamlined integration process that allows you to deploy an Amazon Bedrock-ML connector for multimodal search within minutes. OpenSearch Service console integrations provide AWS CloudFormation templates to automate the steps of Amazon Bedrock model deployment and Amazon Bedrock-ML connector creation in OpenSearch Service.
In the OpenSearch Service console, navigate to Integrations as shown in the following image and search for Titan multi-modal. This returns the CloudFormation template named Integrate with Amazon Bedrock Titan Multi-modal, which you will use in the following steps.Figure 3: Configure domain
Select Configure domain and choose ‘Configure public domain’.
You will be automatically redirected to a CloudFormation template stack as shown in the following image, where most of the configuration is pre-populated for you, including the Amazon Bedrock model, the ML model name, and the AWS Identity and Access Management (IAM) role that is used by Lambda to invoke your OpenSearch domain. Update Amazon OpenSearch Endpoint with your OpenSearch domain endpoint and Model Region with the AWS Region in which your model is available.Figure 4: Create a CloudFormation stack
Before you deploy the stack by clicking ‘Create Stack’, you need to give necessary permissions for the stack to create the ML connector. The CloudFormation template creates a Lambda IAM role for you with the default name LambdaInvokeOpenSearchMLCommonsRole, which you can override if you want to choose a different name. You need to map this IAM role as a Backend role for ml_full_access role in OpenSearch dashboards Security plugin, so that the Lambda function can successfully create the ML connector. To do so,
Login to the OpenSearch Dashboards using the master user credentials that you created as a part of prerequisites. You can find the Dashboards endpoint on your domain dashboard on the OpenSearch Service console.
From the main menu choose Security, Roles, and select the ml_full_access role.
Choose Mapped users, Manage mapping.
Under Backend roles, add the ARN of the Lambda role (arn:aws:iam::<account-id>:role/LambdaInvokeOpenSearchMLCommonsRole) that needs permission to call your domain.
Select Map and confirm the user or role shows up under Mapped users.Figure 5: Set permissions in OpenSearch dashboards security plugin
Return back to the CloudFormation stack console, check the box, ‘I acknowledge that AWS CloudFormation might create IAM resources with customised names‘ and click on ‘Create Stack’.
After the stack is deployed, it will create the Amazon Bedrock-ML connector (ConnectorId) and a model identifier (ModelId). Figure 6: CloudFormation stack outputs
Copy the ModelId from the Outputs tab of the CloudFormation stack starting with prefix ‘OpenSearch-bedrock-mm-’ from your CloudFormation console. You will be using this ModelId in the further steps.
Step 2: Create the OpenSearch ingest pipeline with the text_image_embedding processor
You can create an ingest pipeline with the text_image_embedding processor, which transforms the images and descriptions into embeddings during the indexing process.
In the following request payload, you provide the following parameters to the text_image_embedding processor. Specify which index fields to convert to embeddings, which field should store the vector embeddings, and which ML model to use to perform the vector conversion.
model_id (<model_id>) – The model identifier from the previous step.
Embedding (<vector_embedding>) – The k-NN field that stores the vector embeddings.
field_map (<product_description> and <image_binary>) – The field name of the product description and the product image in binary format.
Step 4: Create the k-NN index and ingest the retail dataset
Create the k-NN index and set the pipeline created in the previous step as the default pipeline. Set index.knn to True to perform an approximate k-NN search. The vector_embedding field type must be mapped as a knn_vector. vector_embedding field dimension must be mapped with the number of dimensions of the vector that the model provides.
Amazon Titan Multimodal Embeddings G1 lets you choose the size of the output vector (either 256, 512, or 1024). In this post, you will be using the default 1024 dimensional vectors from the model. You can check the size of dimensions of the model by selecting ‘Providers’ -> ‘Amazon’ tab -> ‘Titan Multimodal Embeddings G1’ tab -> ‘Model attributes’, from your Bedrock console.
Given the smaller size of the dataset and to bias for better recall, you use the faiss engine with the hnsw algorithm and the default l2 space type for your k-NN index. For more information about different engines and space types, refer to k-NN index.
Finally, you ingest the retail dataset into the k-NN index using a bulk request. For the ingestion code, refer to the step 7, ‘Ingest the dataset into k-NN index using Bulk request‘ in the Jupyter notebook.
Step 5: Perform multimodal search experiments
Perform the following experiments to explore multimodal search and compare results. For text search, use the sample query “Trendy footwear for women” and set the number of results to 5 (size) throughout the experiments.
Experiment 1: Lexical search
This experiment shows you the limitations of simple lexical search and how the results can be improved using multimodal search.
Run a match query against the product_description field by using the following example query payload:
As shown in the preceding figure, the first three results refer to a jacket, glasses, and scarf, which are irrelevant to the query. These were returned because of the matching keywords between the query, “Trendy footwear for women” and the product descriptions, such as “trendy” and “women.” Only the last two results are relevant to the query because they contain footwear items.
Only the last two products fulfil the intent of the query, which was to find products that match all words in the query.
Experiment 2: Multimodal search with only text as input
In this experiment, you will use the Titan Multimodal Embeddings model that you deployed previously and run a neural search with only “Trendy footwear for women” (text) as input.
In the k-NN vector field (vector_embedding) of the neural query, you pass the model_id, query_text, and k value as shown in the following example. k denotes the number of results returned by the k-NN search.
Figure 8: Results from multimodal search using text
Observation:
As shown in the preceding figure, all five results are relevant because each represents a style of footwear. Additionally, the gender preference from the query (women) is also matched in all the results, which indicates that the Titan multimodal embeddings preserved the gender context in both the query and nearest document vectors.
Experiment 3: Multimodal search with only an image as input
In this experiment, you will use only a product image as the input query.
You will use the same neural query and parameters as in the previous experiment but pass the query_image parameter instead of using the query_text parameter. You need to convert the image into binary format and pass the binary string to the query_image parameter:
Figure 9: Image of a woman’s sandal used as the query input
Figure 10: Results from multimodal search using an image
Observation:
As shown in the preceding figure, by passing an image of a woman’s sandal, you were able to retrieve similar footwear styles. Though this experiment provides a different set of results compared to the previous experiment, all the results are highly related to the search query. All the matching documents are similar to the searched product image, not only in terms of the product category (footwear) but also in terms of the style (summer footwear), color, and gender affinity of the product.
Experiment 4: Multimodal search with both text and an image
In this last experiment, you will run the same neural query but pass both the image of a woman’s sandal and the text, “dark color” as inputs.
Figure 11: Image of a woman’s sandal used as part of the query input
As before, you will convert the image into its binary form before passing it to the query:
ML-powered search with OpenSearch and set up you multimodal search solution in your own environment using the guidelines in this post. The solution code is also available on the GitHub repo.
About the Authors
Praveen Mohan Prasad is an Analytics Specialist Technical Account Manager at Amazon Web Services and helps customers with pro-active operational reviews on analytics workloads. Praveen actively researches on applying machine learning to improve search relevance.
Hajer Bouafif is an Analytics Specialist Solutions Architect at Amazon Web Services. She focuses on Amazon OpenSearch Service and helps customers design and build well-architected analytics workloads in diverse industries. Hajer enjoys spending time outdoors and discovering new cultures.
Aruna Govindaraju is an Amazon OpenSearch Specialist Solutions Architect and has worked with many commercial and open-source search engines. She is passionate about search, relevancy, and user experience. Her expertise with correlating end-user signals with search engine behavior has helped many customers improve their search experience. Her favourite pastime is hiking the New England trails and mountains.
As independent software vendors (ISVs) shift to a multi-tenant software-as-a-service (SaaS) model, they commonly adopt a shared infrastructure model to achieve cost and operational efficiency. The more ISVs move into a multi-tenant model, the more concern they may have about the potential for one tenant to access the resources of another tenant. SaaS systems include explicit mechanisms that help ensure that each tenant’s resources—even if they run on shared infrastructure—are isolated.
This is what we refer to as tenant isolation. The idea behind tenant isolation is that your SaaS architecture introduces constructs that tightly control access to resources and block attempts to access the resources of another tenant.
AWS Identity and Access Management (IAM) is a service you can use to securely manage identities and access to AWS services and resources. You can use IAM to implement tenant isolation. With IAM, there are three primary isolation methods, as the How to implement SaaS tenant isolation with ABAC and AWS IAM blog post outlines. These are dynamically-generated IAM policies, role-based access control (RBAC), and attribute-based access control (ABAC). The aforementioned blog post provides an example of using the AWS Security Token Service (AWS STS)AssumeRole API operation and session tags to implement tenant isolation with ABAC. If you aren’t familiar with these concepts, we recommend reading that blog post first to understand the security considerations for this pattern.
In this blog post, you will learn about an alternative approach to implement tenant isolation with ABAC by using the AWS STS AssumeRoleWithWebIdentity API operation and https://aws.amazon.com/tags claim in a JSON Web Token (JWT). The AssumeRoleWithWebIdentity API operation verifies the JWT and generates tenant-scoped temporary security credentials based on the tags in the JWT.
Architecture overview
Let’s look at an example multi-tenant SaaS application that uses a shared infrastructure model.
Figure 1 shows the application architecture and the data access flow. The application uses the AssumeRoleWithWebIdentity API operation to implement tenant isolation.
Figure 1: Example multi-tenant SaaS application
The user navigates to the frontend application.
The frontend application redirects the user to the identity provider for authentication. The identity provider returns a JWT to the frontend application. The frontend application stores the tokens on the server side. The identity provider adds the https://aws.amazon.com/tags claim to the JWT as detailed in the configuration section that follows. The tags claim includes the user’s tenant ID.
The frontend application makes a server-side API call to the backend application with the JWT.
The backend application calls AssumeRoleWithWebIdentity, passing its IAM role Amazon Resource Name (ARN) and the JWT.
AssumeRoleWithWebIdentity verifies the JWT, maps the tenant ID tag in the JWT https://aws.amazon.com/tags claim to a session tag, and returns tenant-scoped temporary security credentials.
The backend API uses the tenant-scoped temporary security credentials to get tenant data. The assumed IAM role’s policy uses the aws:PrincipalTag variable with the tenant ID to scope access.
Configuration
Let’s now have a look at the configuration steps that are needed to use this mechanism.
Step 1: Configure an OIDC provider with tags claim
The AssumeRoleWithWebIdentity API operation requires the JWT to include an https://aws.amazon.com/tags claim. You need to configure your identity provider to include this claim in the JWT it creates.
The following is an example token that includes TenantID as a principal tag (each tag can have a single value). Make sure to replace <TENANT_ID> with your own data.
Amazon Cognito recently launched improvements to the token customization flow that allow you to add arrays, maps, and JSON objects to identity and access tokens at runtime by using a pre token generation AWS Lambda trigger. You need to enable advanced security features and configure your user pool to accept responses to a version 2 Lambda trigger event.
Below is a Lambda trigger code snippet that shows how to add the tags claim to a JWT (an ID token in this example):
Next, you need to create an OpenID Connect (OIDC) identity provider in IAM. IAM OIDC identity providers are entities in IAM that describe an external identity provider service that supports the OIDC standard. You use an IAM OIDC identity provider when you want to establish trust between an OIDC-compatible identity provider and your AWS account.
Before you create an IAM OIDC identity provider, you must register your application with the identity provider to receive a client ID. The client ID (also known as audience) is a unique identifier for your app that is issued to you when you register your app with the identity provider.
Step 3: Create an IAM role
The next step is to create an IAM role that establishes a trust relationship between IAM and your organization’s identity provider. This role must identify your identity provider as a principal (trusted entity) for the purposes of federation. The role also defines what users authenticated by your organization’s identity provider are allowed to do in AWS. When you create the trust policy that indicates who can assume the role, you specify the OIDC provider that you created earlier in IAM.
You can use AWS OIDC condition context keys to write policies that limit the access of federated users to resources that are associated with a specific provider, app, or user. These keys are typically used in the trust policy for a role. Define condition keys using the name of the OIDC provider (<YOUR_PROVIDER_ID>) followed by a claim, for an example client ID from Step 2 (:aud).
The following is an IAM role trust policy example. Make sure to replace <YOUR_PROVIDER_ID> and <AUDIENCE> with your own data.
As an example, the application may store tenant assets in Amazon Simple Storage Service (Amazon S3) by using a prefix per tenant. You can implement tenant isolation by using the aws:PrincipalTag variable in the Resource element of the IAM policy. The IAM policy can reference the principal tags as defined in the JWT https://aws.amazon.com/tags claim.
The following is an IAM policy example. Make sure to replace <S3_BUCKET> with your own data.
How AssumeRoleWithWebIdentity differs from AssumeRole
When using the AssumeRole API operation, the application needs to implement the following steps: 1) Verify the JWT; 2) Extract the tenant ID from the JWT and map it to a session tag; 3) Call AssumeRole to assume the application-provided IAM role. This approach provides applications the flexibility to independently define the tenant ID session tag format.
We see customers wrap this functionality in a shared library to reduce the undifferentiated heavy lifting for the application teams. Each application needs to install this library, which runs sensitive custom code that controls tenant isolation. The SaaS provider needs to develop a library for each programming language they use and run library upgrade campaigns for each application.
When using the AssumeRoleWithWebIdentity API operation, the application calls the API with an IAM role and the JWT. AssumeRoleWithWebIdentity verifies the JWT and generates tenant-scoped temporary security credentials based on the tenant ID tag in the JWT https://aws.amazon.com/tags claim. AWS STS maps the tenant ID tag to a session tag. Customers can use readily available AWS SDKs for multiple programming languages to call the API. See the AssumeRoleWithWebIdentity API operation documentation for more details.
Furthermore, the identity provider now enforces the tenant ID session tag format across applications. This is because AssumeRoleWithWebIdentity uses the tenant ID tag key and value from the JWT as-is.
Conclusion
In this post, we showed how to use the AssumeRoleWithWebIdentity API operation to implement tenant isolation in a multi-tenant SaaS application. The post described the application architecture, data access flow, and how to configure the application to use AssumeRoleWithWebIdentity. Offloading the JWT verification and mapping the tenant ID to session tags helps simplify the application architecture and improve security posture.
Amazon Managed Workflows for Apache Airflow (Amazon MWAA) is a fully managed orchestration service that makes it straightforward to run data processing workflows at scale. Amazon MWAA takes care of operating and scaling Apache Airflow so you can focus on developing workflows. However, although Amazon MWAA provides high availability within an AWS Region through features like Multi-AZ deployment of Airflow components, recovering from a Regional outage requires a multi-Region deployment.
In Part 1 of this series, we highlighted challenges for Amazon MWAA disaster recovery and discussed best practices to improve resiliency. In particular, we discussed two key strategies: backup and restore and warm standby. In this post, we dive deep into the implementation for both strategies and provide a deployable solution to realize the architectures in your own AWS account.
The solution for this post is hosted on GitHub. The README in the repository offers tutorials as well as further workflow details for both backup and restore and warm standby strategies.
Backup and restore architecture
The backup and restore strategy involves periodically backing up Amazon MWAA metadata to Amazon Simple Storage Service (Amazon S3) buckets in the primary Region. The backups are replicated to an S3 bucket in the secondary Region. In case of a failure in the primary Region, a new Amazon MWAA environment is created in the secondary Region and hydrated with the backed-up metadata to restore the workflows.
The project uses the AWS Cloud Development Kit (AWS CDK) and is set up like a standard Python project. Refer to the detailed deployment steps in the README file to deploy it in your own accounts.
The following diagram shows the architecture of the backup and restore strategy and its key components:
Primary Amazon MWAA environment – The environment in the primary Region hosts the workflows
Metadata backup bucket – The bucket in the primary Region stores periodic backups of Airflow metadata tables
Secondary Amazon MWAA environment – This environment is created on-demand during recovery in the secondary Region
Backup workflow – This workflow periodically backups up Airflow metadata to the S3 buckets in the primary Region
Recovery workflow – This workflow monitors the primary Amazon MWAA environment and initiates failover when needed in the secondary Region
Figure 1: The backup restore architecture
There are essentially two workflows that work in conjunction to achieve the backup and restore functionality in this architecture. Let’s explore both workflows in detail and the steps as outlined in Figure 1.
Backup workflow
The backup workflow is responsible for periodically taking a backup of your Airflow metadata tables and storing them in the backup S3 bucket. The steps are as follows:
[1.a] You can deploy the provided solution from your continuous integration and delivery (CI/CD) pipeline. The pipeline includes a DAG deployed to the DAGs S3 bucket, which performs backup of your Airflow metadata. This is the bucket where you host all of your DAGs for your environment.
[1.b] The solution enables cross-Region replication of the DAGs bucket. Any new changes to the primary Region bucket, including DAG files, plugins, and requirements.txt files, are replicated to the secondary Region DAGs bucket. However, for existing objects, a one-time replication needs to be performed using S3 Batch Replication.
[1.c] The DAG deployed to take metadata backup runs periodically. The metadata backup doesn’t include some of the auto-generated tables and the list of tables to be backed up is configurable. By default, the solution backs up variable, connection, slot pool, log, job, DAG run, trigger, task instance, and task fail tables. The backup interval is also configurable and should be based on the Recovery Point Objective (RPO), which is the data loss time during a failure that can be sustained by your business.
[1.d] Similar to the DAGs bucket, the backup bucket is also synced using cross-Region replication, through which the metadata backup becomes available in the secondary Region.
Recovery workflow
The recovery workflow runs periodically in the secondary Region monitoring the primary Amazon MWAA environment. It has two functions:
Store the environment configuration of the primary Amazon MWAA environment in the secondary backup bucket, which is used to recreate an identical Amazon MWAA environment in the secondary Region during failure
Perform the failover when a failure is detected
The following are the steps for when the primary Amazon MWAA environment is healthy (see Figure 1):
[2.b] The workflow, using AWS Lambda, checks Amazon CloudWatch in the primary Region for the SchedulerHeartbeat metrics of the primary Amazon MWAA environment. The environment in the primary Region sends heartbeats to CloudWatch every 5 seconds by default. However, to not invoke a recovery workflow spuriously, we use a default aggregation period of 5 minutes to check the heartbeat metrics. Therefore, it can take up to 5 minutes to detect a primary environment failure.
[2.c] Assuming that the heartbeat was detected in 2.b, the workflow makes the cross-Region GetEnvironment call to the primary Amazon MWAA environment.
[2.d] The response from the GetEnvironment call is stored in the secondary backup S3 bucket to be used in case of a failure in the subsequent iterations of the workflow. This makes sure the latest configuration of your primary environment is used to recreate a new environment in the secondary Region. The workflow completes successfully after storing the configuration.
The following are the steps for the case when the primary environment is unhealthy (see Figure 1):
[2.a] The EventBridge scheduler starts the Step Functions workflow on a provided schedule.
[2.b] The workflow, using Lambda, checks CloudWatch in the primary Region for the scheduler heartbeat metrics and detects failure. The scheduler heartbeat check using the CloudWatch API is the recommended approach to detect failure. However, you can implement a custom strategy for failure detection in the Lambda function such as deploying a DAG to periodically send custom metrics to CloudWatch or other data stores as heartbeats and using the function to check that metrics. With the current CloudWatch-based strategy, the unavailability of the CloudWatch API may spuriously invoke the recovery flow.
[2.c] Skipped
[2.d] The workflow reads the previously stored environment details from the backup S3 bucket.
[2.e] The environment details read from the previous step is used to recreate an identical environment in the secondary Region using the CreateEnvironment API call. The API also needs other secondary Region specific configurations such as VPC, subnets, and security groups that are read from the user-supplied configuration file or environment variables during the solution deployment. The workflow in a polling loop waits until the environment becomes available and invokes the DAG to restore metadata from the backup S3 bucket. This DAG is deployed to the DAGs S3 bucket as a part of the solution deployment.
[2.f] The DAG for restoring metadata completes hydrating the newly created environment and notifies the Step Functions workflow of completion using the task token integration. The new environment now starts running the active workflows and the recovery completes successfully.
Considerations
Consider the following when using the backup and restore method:
Recovery Time Objective – From failure detection to workflows running in the secondary Region, failover can take over 30 minutes. This includes new environment creation, Airflow startup, and metadata restore.
Cost – This strategy avoids the overhead of running a passive environment in the secondary Region. Costs are limited to periodic backup storage, cross-Region data transfer charges, and minimal compute for the recovery workflow.
Data loss – The RPO depends on the backup frequency. There is a design trade-off to consider here. Although shorter intervals between backups can minimize potential data loss, too frequent backups can adversely affect the performance of the metadata database and consequently the primary Airflow environment. Also, the solution can’t recover an actively running workflow midway. All active workflows are started fresh in the secondary Region based on the provided schedule.
Ongoing management – The Amazon MWAA environment and dependencies are automatically kept in sync across Regions in this architecture. As specified in the Step 1.b of the backup workflow, the DAGs S3 bucket will need a one-time deployment of the existing resources for the solution to work.
Warm standby architecture
The warm standby strategy involves deploying identical Amazon MWAA environments in two Regions. Periodic metadata backups from the primary Region are used to rehydrate the standby environment in case of failover.
The project uses the AWS CDK and is set up like a standard Python project. Refer to the detailed deployment steps in the README file to deploy it in your own accounts.
The following diagram shows the architecture of the warm standby strategy and its key components:
Primary Amazon MWAA environment – The environment in the primary Region hosts the workflows during normal operation
Secondary Amazon MWAA environment – The environment in the secondary Region acts as a warm standby ready to take over at any time
Metadata backup bucket – The bucket in the primary Region stores periodic backups of Airflow metadata tables
Replicated backup bucket – The bucket in the secondary Region syncs metadata backups through S3 Cross-Region Replication.
Backup workflow – This workflow periodically backups up Airflow metadata to the S3 buckets in both Regions
Recovery workflow – This workflow monitors the primary environment and initiates failover to the secondary environment when needed
Figure 2: The warm standby architecture
Similar to the backup and restore strategy, the backup workflow (Steps 1a–1d) periodically backups up critical Amazon MWAA metadata to S3 buckets in the primary Region, which is synced in the secondary Region.
The recovery workflow runs periodically in the secondary Region monitoring the primary environment. On failure detection, it initiates the failover procedure. The steps are as follows (see Figure 2):
[2.a] The EventBridge scheduler starts the Step Functions workflow on a provided schedule.
[2.b] The workflow checks CloudWatch in the primary Region for the scheduler heartbeat metrics and detects failure. If the primary environment is healthy, the workflow completes without further actions.
[2.c] The workflow invokes the DAG to restore metadata from the backup S3 bucket.
[2.d] The DAG for restoring metadata completes hydrating the passive environment and notifies the Step Functions workflow of completion using the task token integration. The passive environment starts running the active workflows on the provided schedules.
Because the secondary environment is already warmed up, the failover is faster with recovery times in minutes.
Considerations
Consider the following when using the warm standby method:
Recovery Time Objective – With a warm standby ready, the RTO can be as low as 5 minutes. This includes just the metadata restore and reenabling DAGs in the secondary Region.
Cost – This strategy has an added cost of running similar environments in two Regions at all times. With auto scaling for workers, the warm instance can maintain a minimal footprint; however, the web server and scheduler components of Amazon MWAA will remain active in the secondary environment at all times. The trade-off is significantly lower RTO.
Data loss – Similar to the backup and restore model, the RPO depends on the backup frequency. Faster backup cycles minimize potential data loss but can adversely affect performance of the metadata database and consequently the primary Airflow environment.
Ongoing management – This approach comes with some management overhead. Unlike the backup and restore strategy, any changes to the primary environment configurations need to be manually reapplied to the secondary environment to keep the two environments in sync. Automated synchronization of the secondary environment configurations is a future work.
Shared considerations
Although the backup and restore and warm standby strategies differ in their implementation, they share some common considerations:
Periodically test failover to validate recovery procedures, RTO, and RPO.
Enable Amazon MWAA environment logging to help debug issues during failover.
Automate deployments of environment configurations and disaster recovery workflows through CI/CD pipelines.
Monitor key CloudWatch metrics like SchedulerHeartbeat to detect primary environment failures.
Conclusion
In this series, we discussed how backup and restore and warm standby strategies offer configurable data protection based on your RTO, RPO, and cost requirements. Both use periodic metadata replication and restoration to minimize the area of effect of Regional outages.
Which strategy resonates more with your use case? Feel free to try out our solution and share any feedback or questions in the comments section!
About the Authors
Chandan Rupakheti is a Senior Solutions Architect at AWS. His main focus at AWS lies in the intersection of Analytics, Serverless, and AdTech services. He is a passionate technical leader, researcher, and mentor with a knack for building innovative solutions in the cloud. Outside of his professional life, he loves spending time with his family and friends besides listening and playing music.
Parnab Basak is a Senior Solutions Architect and a Serverless Specialist at AWS. He specializes in creating new solutions that are cloud native using modern software development practices like serverless, DevOps, and analytics. Parnab works closely in the analytics and integration services space helping customers adopt AWS services for their workflow orchestration needs.
Security experts develop CIS Amazon Linux Benchmarks collaboratively, providing guidelines to enhance the security of Amazon Linux-based images. Through a consensus-based process that includes input from a global community of security professionals, these benchmarks are comprehensive and reflective of current cybersecurity challenges and best practices.
When running your container workloads on Amazon EKS, it’s essential to understand the shared responsibility model to clearly know which components fall under your purview to secure. This awareness is essential because it delineates the security responsibilities between you and AWS; although AWS secures the infrastructure, you are responsible for protecting your applications and data. Applying CIS benchmarks to Amazon EKS nodes represents a strategic approach to security enhancements, operational optimizations, and considerations for container host security. This strategy includes updating systems, adhering to modern cryptographic policies, configuring secure filesystems, and disabling unnecessary kernel modules among other recommendations.
Before implementing these benchmarks, I recommend conducting a thorough threat analysis to identify security risks within your environment. This proactive step makes sure that the application of CIS benchmarks is targeted and effective, addressing specific vulnerabilities and threats. Understanding the unique risks in your environment allows you to use the benchmarks strategically to mitigate these risks. This approach helps you to not blindly implement the benchmarks, but to interpret and use them intelligently, tailoring your application to best suit their specific needs. CIS benchmarks should be viewed as a critical tool in your security toolbox, intended for use alongside a broader understanding of your cybersecurity landscape. This balanced and informed application verifies an effective security posture, emphasizing that while CIS benchmarks are an excellent starting point, understanding your environment’s specific security risks is equally important for a comprehensive security strategy.
The benchmarks are widely available, enabling organizations of any size to adopt security measures without significant financial outlays. Furthermore, applying the CIS benchmarks aids in aligning with various security and privacy regulations such as National Institute of Standards and Technology (NIST), Health Insurance Portability and Accountability Act (HIPAA), and Payment Card Industry Data Security Standard (PCI DSS), simplifying compliance efforts.
In this solution, you’ll be implementing the recommendations outlined in the CIS Amazon Linux 2 Benchmark v2.0.0 or Amazon Linux 2023 v1.0.0. To apply the Benchmark’s guidance, you’ll use the Ansible role for the Amazon Linux 2 CIS Baseline, and the Ansible role for Amazon2023 CIS Baseline provided by Ansible Lockdown.
Solution overview
EC2 Image Builder is a fully managed AWS service designed to automate the creation, management and deployment of secure, up-to-date base images. In this solution, we’ll use Image Builder to apply the CIS Amazon Linux Benchmark to an Amazon EKS-optimized Amazon Machine Image (AMI). The resulting AMI will then be used to update your EKS clusters’ node groups. This approach is customizable, allowing you to choose specific security controls to harden your base AMI. However, it’s advisable to review the specific controls offered by this solution and consider how they may interact with your existing workloads and applications to maintain seamless integration and uninterrupted functionality.
Therefore, it’s crucial to understand each security control thoroughly and select those that align with your operational needs and compliance requirements without causing interference.
Additionally, you can specify cluster tags during the deployment of the AWS CloudFormation template. These tags help filter EKS clusters included in the node group update process. I have provided an CloudFormation template to facilitate the provisioning of the necessary resources.
Figure 1: Amazon EKS node group update workflow
As shown in Figure 1, the solution involves the following steps:
Image Builder
The AMI image pipeline clones the Ansible role from the GitHub base on the parent image you specify in the CloudFormation template and applies the controls to the base image.
The pipeline publishes the hardened AMI.
The pipeline validates the benchmarks applied to the base image and publishes the results to an Amazon Simple Storage Service (Amazon S3) bucket. It also invokes Amazon Inspector to run a vulnerability scan on the published image.
The State machine initiation Lambda function extracts the image ID of the published AMI and uses it as the input to initiate the state machine.
State machine
The first state gathers information related to Amazon EKS clusters’ node groups. It creates a new launch template version with the hardened AMI image ID for the node groups that are launched with custom launch template.
The second state uses the new launch template to initiate a node group update on EKS clusters’ node groups.
Image update reminder
A weekly scheduled rule invokes the Image update reminder Lambda function.
The Image update reminder Lambda function retrieves the value for LatestEKSOptimizedAMI from the CloudFormation template and extracts the last modified date of the Amazon EKS-optimized AMI used as the parent image in the Image Builder pipeline. It compares the last modified date of the AMI with the creation date of the latest AMI published by the pipeline. If a new base image is available, it publishes a message to the Image update reminder SNS topic.
The Image update reminder SNS topic sends a message to subscribers notifying them of a new base image. You need to create a new version of your image recipe to update it with the new AMI.
Prerequisites
To follow along with this walkthrough, make sure that you have the following prerequisites in place or the CloudFormation deployment might fail:
In this step, deploy the solution’s resources by creating a CloudFormation stack using the provided CloudFormation template. Sign in to your account and choose an AWS Region where you want to create the stack. Make sure that the Region you choose supports the services used by this solution. To create the stack, follow the steps in Creating a stack on the AWS CloudFormation console. Note that you need to provide values for the parameters defined in the template to deploy the stack. The following table lists the parameters that you need to provide.
Note: To make sure that the AWS Task Orchestrator and Executor (AWSTOE) application functions correctly within Image Builder, and to enable updated nodes with the hardened image to join your EKS cluster, it’s necessary to pass the following minimum Ansible parameters:
Amazon Simple Notification Service (Amazon SNS) is a web service that coordinates and manages the sending and delivery of messages to subscribing endpoints or clients. An SNS topic is a logical access point that acts as a communication channel.
The solution in this post creates two Amazon SNS topics to keep you informed of each step of the process. The following is a list of the topics that the solution creates and their purpose.
AMI status topic – a message is published to this topic upon successful creation of an AMI.
Image update reminder topic – a message is published to this topic if a newer version of the base Amazon EKS-optimized AMI is published by AWS.
You need to manually modify the subscriptions for each topic to receive messages published to that topic.
To modify the subscriptions for the topics created by the CloudFormation template
In the left navigation pane, choose Subscriptions.
On the Subscriptions page, choose Create subscription.
On the Create subscription page, in the Details section, do the following:
For Topic ARN, choose the Amazon Resource Name (ARN) of one of the topics that the CloudFormation topic created.
For Protocol, choose Email.
For Endpoint, enter the endpoint value. In this example, the endpoint is an email address, such as the email address of a distribution list.
Choose Create subscription.
Repeat the preceding steps for the other topic.
Step 4: Run the pipeline
The Image Builder pipeline that the solution creates consists of an image recipe with one component, an infrastructure configuration, and a distribution configuration. I’ve set up the image recipe to create an AMI, select a parent image, and choose components. There’s only one component where building and testing steps are defined. For the building step, the solution applies the CIS Amazon Linux 2 Benchmark Ansible playbook and cleans up the unnecessary files and folders. In the test step, the solution runs Amazon Inspector, a continuous assessment service that scans your AWS workloads for software vulnerabilities and unintended network exposure, and Audit configuration for Amazon Linux 2 CIS. Optionally, you can create your own components and associate them with the image recipe to make further modifications to the base image.
The following is a process overview of the image hardening and instance refresh:
Image hardening – when you start the pipeline, Image Builder creates the required infrastructure to build your AMI, applies the Ansible role (CIS Amazon Linux 2 or Amazon Linux 2023 Benchmark) to the base AMI, and publishes the hardened AMI. A message is published to the AMI status topic as well.
Image testing – after publishing the AMI, Image Builder scans the newly created AMI with Amazon Inspector and reports the findings back. For Amazon Linux 2 parent images, It also runs Audit configuration for Amazon Linux 2 CIS to verify the changes that the Ansible role made to the base AMI and publishes the results to an S3 bucket.
State machine initiation – after a new AMI is successfully published, the AMI status topic invokes the State machine initiation Lambda function. The Lambda function invokes the EKS node group update state machine and passes on the AMI info.
Update node groups – the EKS update node group state machine has two steps:
Gathering node group information – a Lambda function gathers information regarding EKS clusters and their associated Amazon EC2 managed node groups. It only selects and processes node groups launched with custom launch templates that are in Active state. For each node group, the Lambda function creates a new launch template version including the hardened AMI ID published by the pipeline, and user data including bootstrap.sh arguments required for bootstrapping. View Customizing managed nodes with launch templates to learn more about requirements of specifying an AMI ID in the imageId field of EKS node group’s launch template. When you create the CloudFormation stack, if you pass a tag or a list of tags, only clusters with matching tags are processed in this step.
Node group update – the state machine uses the output of the first Lambda function (first state) and starts updating node groups in parallel (second state).
This solution also creates an EventBridge rule that’s invoked weekly. This rule invokes the Image update reminder Lambda function and notifies you if a new version of your base AMI has been published by AWS so that you can run the pipeline and update your hardened AMI. You can check this EventBridge rule by getting it’s Physical ID on the CloudFormation Resources output, identified by ImageUpdateReminderEventBridgeRule.
After the build is finished the Image status will transition to Available in the EC2 Image Builder console, and you will be able to check the new AMI details by choosing the version link, and validate the security findings. The image will then be ready to be distributed across your environment.
Conclusion
In this blog post, I showed you how to create a workflow to harden Amazon EKS-optimized AMIs by using the CIS Amazon Linux 2 or Amazon Linux 2023 Benchmark and to automate the update of EKS node groups. This automated workflow has several advantages. First, it helps ensure a consistent and standardized process for image hardening, reducing potential human errors and inconsistencies. By automating the entire process, you can apply security and compliance standards across your instances. Second, the tight integration with AWS Step Functions enables smooth, orchestrated updates to the EKS node groups, enhancing the reliability and predictability of deployments. This automation also reduces manual intervention, helping you save time so that your teams can focus on more value-driven tasks. Moreover, this systematic approach helps to enhance the security posture of your Amazon EKS workloads because you can address vulnerabilities rapidly and systematically, helping to keep the environment resilient against potential threats.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Based on discussions with several SAP on AWS customers, we have discovered that the number of SAP administration or operational task requirements often exceed the capacity of the available team. Due to lack of time, resources, and heavy focus on operations, strategic initiatives like digital transformations often remain unaddressed. Although 1P and 3P automation solutions are available, many organizations do not adopt them, due to cost, internal processes, complexities associated with managing multiple-vendor tooling, etc. While some SAP BASIS teams have successfully automated some tasks, the level of effort and skill set to develop custom scripts is not widely available, in some cases due to a skills gap or insufficient knowledge in scripting. In this blog post we will use Amazon Q Developer, a generative AI coding assistant, and use natural language to create SAP operational automation in a more productive fashion.
Walkthrough
Amazon Q Developer acts as a bridge between logical comprehension and practical coding implementation. It enables SAP BASIS administrators to translate their operational understanding into code by interpreting their logic, articulated in natural language. This approach allows us to accelerate the development process of automation scripts, democratizing script development to a broader base of infrastructure and application administrators. In this case, Amazon Q provides coding suggestions by converting natural English language explanations of logic into operational code, such as an automation script for the operational activity (e.g., Start and Stop of SAP).
The solution is orchestrated in two stages:
Administrators use Q Developer using natural language to formulate a shell script to perform start and stop operations on a single Amazon EC2 instance.
Q Developer validates inputs, assessment of system installation, and execution of start/stop commands.
Prerequisites
For the walkthrough, we are using VS Codium for our integrated development environment (IDE) with the latest Amazon Q Developer extension installed. However, you may use any of the supported IDEs.
Prior to starting, it may be important to model the entire workflow. For example, the script may need a number of conditions, checks, and logical considerations. However, for the purposes of our scenario, we focus on three specific conditions, checks, and logical processes. For your specific use case, we recommend incorporating additional logical steps, if needed.
The script we will write has 3 arguments in order to Start/Stop the SAP System.
The SAP System ID (SID)
The SAP Instance Number
The command ‘start’ or ‘stop’ – will start or stop the SAP system.
To run the script the command should look like the example below:
scriptname.sh <SID> <InstanceNumber> <start/stop>
There are also four conditions, checks, and logic blocks in the script,
First, check if the command has 3 arguments. If any are missing, the system will not be able to perform the intended action.
Second, check if the SAP system (SID) we are trying to manage is available in the current EC2 instance.
Third, the SAP Instance Number is checked in the current EC2 instance.
Lastly, the script needs to tell the system which command to run, based on the third argument (e.g., start or stop).
Important: Comments in Shell scripts start with a ‘#’ sign, and the arguments are indicated by a ‘$<n>’ format; n being the sequence number of the argument. So, in our case:
Now that we have established the structure of how to call the script and what arguments we are going to pass, lets write the comments in English to get code recommendations from Amazon Q.
Getting Started
1. In VS Codium, create a ‘New File’ for our script. Assign a file name and make sure the file extension ends with a ‘.sh’ (e.g., startstopsap.sh).
Below is an example of the comments we used for our logic. Copy paste this into the file.
Info: The first line #!/bin/bash tells the system to execute the script using the Bash shell. The rest of the lines tell what the script needs to check, the logic it needs to follow and the commands it needs to run.
#!/bin/bash
#This is a script that is going to start and stop an SAP instance based on the given inputs to the script
#The script will receive 3 inputs. <SID> <InstanceNumber> <start/stop>
#If the script did not get 3 inputs, the script will fail with showing the usage guidance.
#Check if the file "/usr/sap/sapservices" exists. If not, fail.
#We will check if the given SID is installed in this server by searching the SID in the file "/usr/sap/sapservices"  If it does not exist, fail, otherwise continue.
#Then we will check if the given instance number is installed in this server by searching the Instance Number in the file "/usr/sap/sapservices”. If it does not exist, fail, otherwise continue.
#If all conditions met, check the third output and if it's start, start the sap system using "sapcontrol -nr InstanceNumber -function Start"
#If all conditions met, see the third output and if it's stop, stop the sap system using "sapcontrol -nr InstanceNumber -function Stop"
#Then wait for 2 minutes for the stop command to complete (if stop)
#Remove the ipcs (if stop) by the command “cleanipc InstanceNumber remove”
#If the third input is not start or stop, fail.
#End the script.
2. Type #Check Input and press Enter, Q will start making code suggestions. If it does not, you can manually invoke suggestions with ‘Option+C’ on Mac or ‘Alt+C’ on Windows.
Figure 1 – Amazon Q Developer Suggestions
3. To accept suggested code, either press ‘Tab’ or click on ‘Accept’.
The ‘< 1/2 >’ means that there are two suggestions and you may accept the one that is most appropriate for the scenario. Toggle between the suggestions using right and left arrows on your keyboard.
We will accept the code and then press Enter to move to the next line. As soon as you press the Enter key, the next line of code will be suggested.
Important: Amazon Q Developer is non-deterministic, which means that code suggestions produced may be different from what is shown in the blog. If the suggestions look different for you, you can use the arrows on your keyboard to toggle between recommendations, as shown below.
4. Accept the next block of code and eventually close the IF loop. Press Enter.
Figure 2 – Reviewing Suggestions
5. Based on comments in the file, Q should should have enough context to suggest what needs to be done next. The script should check if the /usr/sap/sapservices file exists.
Figure 3 – Checking dependencies
6. Once you accept the code, Q will propose the next lines. Keep accepting the appropriate lines of code until all required sections are completed. Once the script is ready, it should look similar to what is depicted below. Save the script.
Figure 4 – First part of the script
Figure 5 – Second part of the script
Figure 6 – Third part of the script
7. Go to the EC2 instance hosting SAP and use your local text editor (e.g., vi) to create a file with the “.sh” file extension. Let’s say the file is named SAPStopStart.sh
8. Paste the contents of the code from your file in the IDE.
9. Save the file and add execute permissions to the file by running chmod +x SAPStopStart.sh
10. To run the script, use the appropriate arguments as shown below.
Although in this blog post we used a simple example of starting and stopping an SAP system, Amazon Q Developer can be extended to a broader spectrum of SAP operational scenarios. Q Developer’s capabilities can be used to harness a broad range of SAP-related use cases, such as kernel patching, database patching, and beyond. In addition to code suggestions, Q Developer offers a security scanning feature, which can be used for fortifying application security. Amazon Q Developer is available in Pro and Free Tiers and does not require an AWS Account to get started. For the purpose of this blog, we used the Amazon Q Developer Free Tier. To learn more about Amazon Q Developer, click to go to its product page.
In today’s data-driven world, organizations are continually confronted with the task of managing extensive volumes of data securely and efficiently. Whether it’s customer information, sales records, or sensor data from Internet of Things (IoT) devices, the importance of handling and storing data at scale with ease of use is paramount.
OpenSearch Service is a fully managed, open source search and analytics engine that helps you with ingesting, searching, and analyzing large datasets quickly and efficiently. OpenSearch Service enables you to quickly deploy, operate, and scale OpenSearch clusters. It continues to be a tool of choice for a wide variety of use cases such as log analytics, real-time application monitoring, clickstream analysis, website search, and more.
OpenSearch Dashboards is a visualization and exploration tool that allows you to create, manage, and interact with visuals, dashboards, and reports based on the data indexed in your OpenSearch cluster.
Visualize data in OpenSearch Dashboards
Visualizing the data in OpenSearch Dashboards involves the following steps:
Ingest data – Before you can visualize data, you need to ingest the data into an OpenSearch Service index in an OpenSearch Service domain or Amazon OpenSearch Serverless collection and define the mapping for the index. You can specify the data types of fields and how they should be analyzed; if nothing is specified, OpenSearch Service automatically detects the data type of each field and creates a dynamic mapping for your index by default.
Create an index pattern – After you index the data into your OpenSearch Service domain, you need to create an index pattern that enables OpenSearch Dashboards to read the data stored in the domain. This pattern can be based on index names, aliases, or wildcard expressions. You can configure the index pattern by specifying the timestamp field (if applicable) and other settings that are relevant to your data.
Create visualizations – You can create visuals that represent your data in meaningful ways. Common types of visuals include line charts, bar charts, pie charts, maps, and tables. You can also create more complex visualizations like heatmaps and geospatial representations.
Ingest data with OpenSearch Ingestion
Ingesting data into OpenSearch Service can be challenging because it involves a number of steps, including collecting, converting, mapping, and loading data from different data sources into your OpenSearch Service index. Traditionally, this data was ingested using integrations with Amazon Data Firehose,Logstash, Data Prepper, Amazon CloudWatch, or AWS IoT.
The OpenSearch Ingestion feature of OpenSearch Service introduced in April 2023 makes ingesting and processing petabyte-scale data into OpenSearch Service straightforward. OpenSearch Ingestion is a fully managed, serverless data collector that allows you to ingest, filter, enrich, and route data to an OpenSearch Service domain or OpenSearch Serverless collection. You configure your data producers to send data to OpenSearch Ingestion, which automatically delivers the data to the domain or collection that you specify. You can configure OpenSearch Ingestion to transform your data before delivering it.
OpenSearch Ingestion scales automatically to meet the requirements of your most demanding workloads, helping you focus on your business logic while abstracting away the complexity of managing complex data pipelines. It’s powered by Data Prepper, an open source streaming Extract, Transform, Load (ETL) tool that can filter, enrich, transform, normalize, and aggregate data for downstream analysis and visualization.
OpenSearch Ingestion uses pipelines as a mechanism that consists of three major components:
Source – The input component of a pipeline. It defines the mechanism through which a pipeline consumes records.
Processors – The intermediate processing units that can filter, transform, and enrich records into a desired format before publishing them to the sink. The processor is an optional component of a pipeline.
Sink – The output component of a pipeline. It defines one or more destinations to which a pipeline publishes records. A sink can also be another pipeline, which allows you to chain multiple pipelines together.
You can process data files written in S3 buckets in two ways: by processing the files written to Amazon S3 in near real time using Amazon Simple Queue Service (Amazon SQS), or with the scheduled scans approach, in which you process the data files in batches using one-time or recurring scheduled scan configurations.
In the following section, we provide an overview of the solution and guide you through the steps to ingest CSV files from Amazon S3 into OpenSearch Service using the S3-SQS approach in OpenSearch Ingestion. Additionally, we demonstrate how to visualize the ingested data using OpenSearch Dashboards.
Solution overview
The following diagram outlines the workflow of ingesting CSV files from Amazon S3 into OpenSearch Service.
Amazon SQS receives an Amazon S3 event notification as a JSON file with metadata such as the S3 bucket name, object key, and timestamp.
The OpenSearch Ingestion pipeline receives the message from Amazon SQS, loads the files from Amazon S3, and parses the CSV data from the message into columns. It then creates an index in the OpenSearch Service domain and adds the data to the index.
Lastly, you create an index pattern and visualize the ingested data using OpenSearch Dashboards.
OpenSearch Ingestion provides a serverless ingestion framework to effortlessly ingest data into OpenSearch Service with just a few clicks.
Prerequisites
Make sure you meet the following prerequisites:
You must have access to the AWS account in which you wish to set up this solution.
Amazon SQS offers a secure, durable, and available hosted queue that lets you integrate and decouple distributed software systems and components. Create a standard SQS queue and provide a descriptive name for the queue, then update the access policy by navigating to the Amazon SQS console, opening the details of your queue, and editing the policy on the Advanced tab.
The following is a sample access policy you could use for reference to update the access policy:
SQS FIFO (First-In-First-Out) queues aren’t supported as an Amazon S3 event notification destination. To send a notification for an Amazon S3 event to an SQS FIFO queue, you can use Amazon EventBridge.
Create an S3 bucket and enable Amazon S3 event notification
Create an S3 bucket that will be the source for CSV files and enable Amazon S3 notifications. The Amazon S3 notification invokes an action in response to a specific event in the bucket. In this workflow, whenever there in an event of type S3:ObjectCreated:*, the event sends an Amazon S3 notification to the SQS queue created in the previous step. Refer to Walkthrough: Configuring a bucket for notifications (SNS topic or SQS queue) to configure the Amazon S3 notification in your S3 bucket.
Create an IAM policy for the OpenSearch Ingest pipeline
A trust relationship defines which entities (such as AWS accounts, IAM users, roles, or services) are allowed to assume a particular IAM role. Create an IAM role for the OpenSearch Ingestion pipeline (osis-pipelines.amazonaws.com), attach the IAM policy created in the previous step, and add the trust relationship to allow OpenSearch Ingestion pipelines to write to domains.
Configure an OpenSearch Ingestion pipeline
A pipeline is the mechanism that OpenSearch Ingestion uses to move data from its source (where the data comes from) to its sink (where the data goes). OpenSearch Ingestion provides out-of-the-box configuration blueprints to help you quickly set up pipelines without having to author a configuration from scratch. Set up the S3 bucket as the source and OpenSearch Service domain as the sink in the OpenSearch Ingestion pipeline with the following blueprint:
On the OpenSearch Service console, create a pipeline with the name my-pipeline. Keep the default capacity settings and enter the preceding pipeline configuration in the Pipeline configuration section.
Update the configuration setting with the previously created IAM roles to read from Amazon S3 and write into OpenSearch Service, the SQS queue URL, and the OpenSearch Service domain endpoint.
Validate the solution
To validate this solution, you can use the dataset SaaS-Sales.csv. This dataset contains transaction data from a software as a service (SaaS) company selling sales and marketing software to other companies (B2B). You can initiate this workflow by uploading the SaaS-Sales.csv file to the S3 bucket. This invokes the pipeline and creates an index in the OpenSearch Service domain you created earlier.
Follow these steps to validate the data using OpenSearch Dashboards.
First, you create an index pattern. An index pattern is a way to define a logical grouping of indexes that share a common naming convention. This allows you to search and analyze data across all matching indexes using a single query or visualization. For example, if you named your indexes csv-ingest-index-2024-01-01 and csv-ingest-index-2024-01-02 while ingesting the monthly sales data, you can define an index pattern as csv-* to encompass all these indexes.
Next, you create a visualization. Visualizations are powerful tools to explore and analyze data stored in OpenSearch indexes. You can gather these visualizations into a real time OpenSearch dashboard. An OpenSearch dashboard provides a user-friendly interface for creating various types of visualizations such as charts, graphs, maps, and dashboards to gain insights from data.
You can visualize the sales data by industry with a pie chart with the index pattern created in the previous step. To create a pie chart, update the metrics details as follows on the Data tab:
Set Metrics to Slice
Set Aggregation to Sum
Set Field to sales
To view the industry-wise sales details in the pie chart, add a new bucket on the Data tab as follows:
When you’re done exploring OpenSearch Ingestion and OpenSearch Dashboards, you can delete the resources you created to avoid incurring further costs.
Conclusion
In this post, you learned how to ingest CSV files efficiently from S3 buckets into OpenSearch Service with the OpenSearch Ingestion feature in a serverless way without requiring a third-party agent. You also learned how to analyze the ingested data using OpenSearch dashboard visualizations. You can now explore extending this solution to build OpenSearch Ingestion pipelines to load your data and derive insights with OpenSearch Dashboards.
About the Authors
Sharmila Shanmugam is a Solutions Architect at Amazon Web Services. She is passionate about solving the customers’ business challenges with technology and automation and reduce the operational overhead. In her current role, she helps customers across industries in their digital transformation journey and build secure, scalable, performant and optimized workloads on AWS.
Harsh Bansal is an Analytics Solutions Architect with Amazon Web Services. In his role, he collaborates closely with clients, assisting in their migration to cloud platforms and optimizing cluster setups to enhance performance and reduce costs. Before joining AWS, he supported clients in leveraging OpenSearch and Elasticsearch for diverse search and log analytics requirements.
Rohit Kumar works as a Cloud Support Engineer in the Support Engineering team at Amazon Web Services. He focuses on Amazon OpenSearch Service, offering guidance and technical help to customers, helping them create scalable, highly available, and secure solutions on AWS Cloud. Outside of work, Rohit enjoys watching or playing cricket. He also loves traveling and discovering new places. Essentially, his routine revolves around eating, traveling, cricket, and repeating the cycle.
Amazon Web Services (AWS) provides tools that simplify automation and monitoring for compliance with security standards, such as the NIST SP 800-53 Rev. 5 Operational Best Practices. Organizations can set preventative and proactive controls to help ensure that noncompliant resources aren’t deployed. Detective and responsive controls notify stakeholders of misconfigurations immediately and automate fixes, thus minimizing the time to resolution (TTR).
By layering the solutions outlined in this blog post, you can increase the probability that your deployments stay continuously compliant with the National Institute of Standards and Technology (NIST) SP 800-53 security standard, and you can simplify reporting on that compliance. In this post, we walk you through the following tools to get started on your continuous compliance journey:
This post covers quite a few solutions, and these solutions operate in different parts of the security pillar of the AWS Well-Architected Framework. It might take some iterations to get your desired results, but we encourage you to start small, find your focus areas, and implement layered iterative changes to address them.
For example, if your organization has experienced events involving public Amazon Simple Storage Service (Amazon S3) buckets that can lead to data exposure, focus your efforts across the different control types to address that issue first. Then move on to other areas. Those steps might look similar to the following:
Use Security Hub and Prowler to find your public buckets and monitor patterns over a predetermined time period to discover trends and perhaps an organizational root cause.
Apply IAM policies and SCPs to specific organizational units (OUs) and principals to help prevent the creation of public buckets and the changing of AWS account-level controls.
Set up Automated Security Response (ASR) on AWS and then test and implement the automatic remediation feature for only S3 findings.
Remove direct human access to production accounts and OUs. Require infrastructure as code (IaC) to pass through a pipeline where CloudFormation Guard scans IaC for misconfigurations before deployment into production environments.
Detective controls
Implement your detective controls first. Use them to identify misconfigurations and your priority areas to address. Detective controls are security controls that are designed to detect, log, and alert after an event has occurred. Detective controls are a foundational part of governance frameworks. These guardrails are a second line of defense, notifying you of security issues that bypassed the preventative controls.
Security Hub NIST SP 800-53 security standard
Security Hub consumes, aggregates, and analyzes security findings from various supported AWS and third-party products. It functions as a dashboard for security and compliance in your AWS environment. Security Hub also generates its own findings by running automated and continuous security checks against rules. The rules are represented by security controls. The controls might, in turn, be enabled in one or more security standards. The controls help you determine whether the requirements in a standard are being met. Security Hub provides controls that support specific NIST SP 800-53 requirements. Unlike other frameworks, NIST SP 800-53 isn’t prescriptive about how its requirements should be evaluated. Instead, the framework provides guidelines, and the Security Hub NIST SP 800-53 controls represent the service’s understanding of them.
Using this step-by-step guide, enable Security Hub for your organization in AWS Organizations. Configure the NIST SP 800-53 security standard for all accounts, in all AWS Regions that are required to be monitored for compliance, in your organization by using the new centralized configuration feature; or if your organization uses AWS GovCloud (US), by using this multi-account script. Use the findings from the NIST SP 800-53 security standard in your delegated administrator account to monitor NIST SP 800-53 compliance across your entire organization, or a list of specific accounts.
Figure 1 shows the Security Standard console page, where users of the Security Hub Security Standard feature can see an overview of their security score against a selected security standard.
Figure 1: Security Hub security standard console
On this console page, you can select each control that is checked by a Security Hub Security Standard, such as the NIST 800-53 Rev. 5 standard, to find detailed information about the check and which NIST controls it maps to, as shown in Figure 2.
Figure 2: Security standard check detail
After you enable Security Hub with the NIST SP 800-53 security standard, you can link responsive controls such as the Automated Security Response (ASR), which is covered later in this blog post, to Amazon EventBridge rules to listen for Security Hub findings as they come in.
Prowler
Prowler is an open source security tool that you can use to perform assessments against AWS Cloud security recommendations, along with audits, incident response, continuous monitoring, hardening, and forensics readiness. The tool is a Python script that you can run anywhere that an up-to-date Python installation is located—this could be a workstation, an Amazon Elastic Compute Cloud (Amazon EC2) instance, AWS Fargate or another container, AWS CodeBuild, AWS CloudShell, AWS Cloud9, or another compute option.
Figure 3 shows Prowler being used to perform a scan.
Figure 3: Prowler CLI in action
Prowler works well as a complement to the Security Hub NIST SP 800-53 Rev. 5 security standard. The tool has a native Security Hub integration and can send its findings to your Security Hub findings dashboard. You can also use Prowler as a standalone compliance scanning tool in partitions where Security Hub or the security standards aren’t yet available.
At the time of writing, Prowler has over 300 checks across 64 AWS services.
In addition to integrations with Security Hub and computer-based outputs, Prowler can produce fully interactive HTML reports that you can use to sort, filter, and dive deeper into findings. You can then share these compliance status reports with compliance personnel. Some organizations run automatically recurring Prowler reports and use Amazon Simple Notification Service (Amazon SNS) to email the results directly to their compliance personnel.
Get started with Prowler by reviewing the Prowler Open Source documentation that contains tutorials for specific providers and commands that you can copy and paste.
Preventative controls
Preventative controls are security controls that are designed to prevent an event from occurring in the first place. These guardrails are a first line of defense to help prevent unauthorized access or unwanted changes to your network. Service control policies (SCPs) and IAM controls are the best way to help prevent principals in your AWS environment (whether they are human or nonhuman) from creating noncompliant or misconfigured resources.
IAM
In the ideal environment, principals (both human and nonhuman) have the least amount of privilege that they need to reach operational objectives. Ideally, humans would at the most only have read-only access to production environments. AWS resources would be created through IaC that runs through a DevSecOps pipeline where policy-as-code checks review resources for compliance against your policies before deployment. DevSecOps pipeline roles should have IAM policies that prevent the deployment of resources that don’t conform to your organization’s compliance strategy. Use IAM conditions wherever possible to help ensure that only requests that match specific, predefined parameters are allowed.
The following policy is a simple example of a Deny policy that uses Amazon Relational Database Service (Amazon RDS) condition keys to help prevent the creation of unencrypted RDS instances and clusters. Most AWS services support condition keys that allow for evaluating the presence of specific service settings. Use these condition keys to help ensure that key security features, such as encryption, are set during a resource creation call.
You can use an SCP to specify the maximum permissions for member accounts in your organization. You can restrict which AWS services, resources, and individual API actions the users and roles in each member account can access. You can also define conditions for when to restrict access to AWS services, resources, and API actions. If you haven’t used SCPs before and want to learn more, see How to use service control policies to set permission guardrails across accounts in your AWS Organization.
Use SCPs to help prevent common misconfigurations mapped to NIST SP 800-53 controls, such as the following:
Prevent governed accounts from leaving the organization or turning off security monitoring services.
Build protections and contextual access controls around privileged principals.
Mitigate the risk of data mishandling by enforcing data perimeters and requiring encryption on data at rest.
Although SCPs aren’t the optimal choice for preventing every misconfiguration, they can help prevent many of them. As a feature of AWS Organizations, SCPs provide inheritable controls to member accounts of the OUs that they are applied to. For deployments in Regions where AWS Organizations isn’t available, you can use IAM policies and permissions boundaries to achieve preventative functionality that is similar to what SCPs provide.
The following is an example of policy mapping statements to NIST controls or control families. Note the placeholder values, which you will need to replace with your own information before use. Note that the SIDs map to Security Hub NIST 800-53 Security Standard control numbers or NIST control families.
For a collection of SCP examples that are ready for your testing, modification, and adoption, see the service-control-policy-examples GitHub repository, which includes examples of Region and service restrictions.
You should thoroughly test SCPs against development OUs and accounts before you deploy them against production OUs and accounts.
Proactive controls
Proactive controls are security controls that are designed to prevent the creation of noncompliant resources. These controls can reduce the number of security events that responsive and detective controls handle. These controls help ensure that deployed resources are compliant before they are deployed; therefore, there is no detection event that requires response or remediation.
CloudFormation Guard
CloudFormation Guard (cfn-guard) is an open source, general-purpose, policy-as-code evaluation tool. Use cfn-guard to scan Information as Code (IaC) against a collection of policies, defined as JSON, before deployment of resources into an environment.
Cfn-guard can scan CloudFormation templates, Terraform plans, Kubernetes configurations, and AWS Cloud Development Kit (AWS CDK) output. Cfn-guard is fully extensible, so your teams can choose the rules that they want to enforce, and even write their own declarative rules in a YAML-based format. Ideally, the resources deployed into a production environment on AWS flow through a DevSecOps pipeline. Use cfn_guard in your pipeline to define what is and is not acceptable for deployment, and help prevent misconfigured resources from deploying. Developers can also use cfn_guard on their local command line, or as a pre-commit hook to move the feedback timeline even further “left” in the development cycle.
Use policy as code to help prevent the deployment of noncompliant resources. When you implement policy as code in the DevOps cycle, you can help shorten the development and feedback cycle and reduce the burden on security teams. The CloudFormation team maintains a GitHub repo of cfn-guard rules and mappings, ready for rapid testing and adoption by your teams.
Figure 4 shows how you can use Guard with the NIST 800-53 cfn_guard Rule Mapping to scan infrastructure as code against NIST 800-53 mapped rules.
Figure 4: CloudFormation Guard scan results
You should implement policy as code as pre-commit checks so that developers get prompt feedback, and in DevSecOps pipelines to help prevent deployment of noncompliant resources. These checks typically run as Bash scripts in a continuous integration and continuous delivery (CI/CD) pipeline such as AWS CodeBuild or GitLab CI. To learn more, see Integrating AWS CloudFormation Guard into CI/CD pipelines.
Many other third-party policy-as-code tools are available and include NIST SP 800-53 compliance policies. If cfn-guard doesn’t meet your needs, or if you are looking for a more native integration with the AWS CDK, for example, see the NIST-800-53 rev 5 rules pack in cdk-nag.
Responsive controls
Responsive controls are designed to drive remediation of adverse events or deviations from your security baseline. Examples of technical responsive controls include setting more stringent security group rules after a security group is created, setting a public access block on a bucket automatically if it’s removed, patching a system, quarantining a resource exhibiting anomalous behavior, shutting down a process, or rebooting a system.
Automated Security Response on AWS
The Automated Security Response on AWS (ASR) is an add-on that works with Security Hub and provides predefined response and remediation actions based on industry compliance standards and current recommendations for security threats. This AWS solution creates playbooks so you can choose what you want to deploy in your Security Hub administrator account (which is typically your Security Tooling account, in our recommended multi-account architecture). Each playbook contains the necessary actions to start the remediation workflow within the account holding the affected resource. Using ASR, you can resolve common security findings and improve your security posture on AWS. Rather than having to review findings and search for noncompliant resources across many accounts, security teams can view and mitigate findings from the Security Hub console of the delegated administrator.
The architecture diagram in Figure 5 shows the different portions of the solution, deployed into both the Administrator account and member accounts.
Figure 5: ASR architecture diagram
The high-level process flow for the solution components deployed with the AWS CloudFormation template is as follows:
Detect – AWS Security Hub provides customers with a comprehensive view of their AWS security state. This service helps them to measure their environment against security industry standards and best practices. It works by collecting events and data from other AWS services, such as AWS Config, Amazon GuardDuty, and AWS Firewall Manager. These events and data are analyzed against security standards, such as the CIS AWS Foundations Benchmark. Exceptions are asserted as findings in the Security Hub console. New findings are sent as Amazon EventBridge events.
Initiate – You can initiate events against findings by using custom actions, which result in Amazon EventBridge events. Security Hub Custom Actions and EventBridge rules initiate Automated Security Response on AWS playbooks to address findings. One EventBridge rule is deployed to match the custom action event, and one EventBridge event rule is deployed for each supported control (deactivated by default) to match the real-time finding event. Automated remediation can be initiated through the Security Hub Custom Action menu, or, after careful testing in a non-production environment, automated remediations can be activated. This can be activated per remediation—it isn’t necessary to activate automatic initiations on all remediations.
Orchestrate – Using cross-account IAM roles, Step Functions in the admin account invokes the remediation in the member account that contains the resource that produced the security finding.
Log – The playbook logs the results to an Amazon CloudWatch Logs group, sends a notification to an Amazon SNS topic, and updates the Security Hub finding. An audit trail of actions taken is maintained in the finding notes. On the Security Hub dashboard, the finding workflow status is changed from NEW to either NOTIFIED or RESOLVED. The security finding notes are updated to reflect the remediation that was performed.
The NIST SP 800-53 Playbook contains 52 remediations to help security and compliance teams respond to misconfigured resources. Security teams have a choice between launching these remediations manually, or enabling the associated EventBridge rules to allow the automations to bring resources back into a compliant state until further action can be taken on them. When a resource doesn’t align with the Security Hub NIST SP 800-53 security standard automated checks and the finding appears in Security Hub, you can use ASR to move the resource back into a compliant state. Remediations are available for 17 of the common core services for most AWS workloads.
Figure 6 shows how you can remediate a finding with ASR by selecting the finding in Security Hub and sending it to the created custom action.
Figure 6: ASR Security Hub custom action
Findings generated from the Security Hub NIST SP 800-53 security standard are displayed in the Security Hub findings or security standard dashboards. Security teams can review the findings and choose which ones to send to ASR for remediation. The general architecture of ASR consists of EventBridge rules to listen for the Security Hub custom action, an AWS Step Functions workflow to control the process and implementation, and several AWS Systems Manager documents (SSM documents) and AWS Lambda functions to perform the remediation. This serverless, step-based approach is a non-brittle, low-maintenance way to keep persistent remediation resources in an account, and to pay for their use only as needed. Although you can choose to fork and customize ASR, it’s a fully developed AWS solution that receives regular bug fixes and feature updates.
To get started, see the ASR Implementation Guide, which will walk you through configuration and deployment.
Several options are available to concisely gather results into digestible reports that compliance professionals can use as artifacts during the Risk Management Framework (RMF) process when seeking an Authorization to Operate (ATO). By automating reporting and delegating least-privilege access to compliance personnel, security teams may be able to reduce time spent reporting compliance status to auditors or oversight personnel.
Let your compliance folks in
Remove some of the burden of reporting from your security engineers, and give compliance teams read-only access to your Security Hub dashboard in your Security Tooling account. Enabling compliance teams with read-only access through AWS IAM Identity Center (or another sign-on solution) simplifies governance while still maintaining the principle of least privilege. By adding compliance personnel to the AWSSecurityAudit managed permission set in IAM Identity Center, or granting this policy to IAM principals, these users gain visibility into operational accounts without the ability to make configuration changes. Compliance teams can self-serve the security posture details and audit trails that they need for reporting purposes.
Meanwhile, administrative teams are freed from regularly gathering and preparing security reports, so they can focus on operating compliant workloads across their organization. The AWSSecurityAudit permission set grants read-only access to security services such as Security Hub, AWS Config, Amazon GuardDuty, and AWS IAM Access Analyzer. This provides compliance teams with wide observability into policies, configuration history, threat detection, and access patterns—without the privilege to impact resources or alter configurations. This ultimately helps to strengthen your overall security posture.
For more information about AWS managed policies, such as the AWSSecurityAudit managed policy, see the AWS managed policies.
To learn more about permission sets in IAM Identity Center, see Permission sets.
AWS Audit Manager
AWS Audit Manager helps you continually audit your AWS usage to simplify how you manage risk and compliance with regulations and industry standards. Audit Manager automates evidence collection so you can more easily assess whether your policies, procedures, and activities—also known as controls—are operating effectively. When it’s time for an audit, Audit Manager helps you manage stakeholder reviews of your controls. This means that you can build audit-ready reports with much less manual effort.
Audit Manager provides prebuilt frameworks that structure and automate assessments for a given compliance standard or regulation, including NIST 800-53 Rev. 5. Frameworks include a prebuilt collection of controls with descriptions and testing procedures. These controls are grouped according to the requirements of the specified compliance standard or regulation. You can also customize frameworks and controls to support internal audits according to your specific requirements.
For more information about using Audit Manager to generate automated compliance reports, see the AWS Audit Manager User Guide.
Security Hub Compliance Analyzer (SHCA)
Security Hub is the premier security information aggregating tool on AWS, offering automated security checks that align with NIST SP 800-53 Rev. 5. This alignment is particularly critical for organizations that use the Security Hub NIST SP 800-53 Rev. 5 framework. Each control within this framework is pivotal for documenting the compliance status of cloud environments, focusing on key aspects such as:
Related requirements – For example, NIST.800-53.r5 CM-2 and NIST.800-53.r5 CM-2(2)
Severity – Assessment of potential impact
Description – Detailed control explanation
Remediation – Strategies for addressing and mitigating issues
Such comprehensive information is crucial in the accreditation and continuous monitoring of cloud environments.
To further augment the utility of this data for customers seeking to compile artifacts and articulate compliance status, the AWS ProServe team has introduced the Security Hub Compliance Analyzer (SHCA).
SHCA is engineered to streamline the RMF process. It reduces manual effort, delivers extensive reports for informed decision making, and helps assure continuous adherence to NIST SP 800-53 standards. This is achieved through a four-step methodology:
Active findings collection – Compiles ACTIVE findings from Security Hub that are assessed using NIST SP 800-53 Rev. 5 standards.
Results transformation – Transforms these findings into formats that are both user-friendly and compatible with RMF tools, facilitating understanding and utilization by customers.
Data analysis and compliance documentation – Performs an in-depth analysis of these findings to pinpoint compliance and security shortfalls. Produces comprehensive compliance reports, summaries, and narratives that accurately represent the status of compliance for each NIST SP 800-53 Rev. 5 control.
Findings archival – Assembles and archives the current findings for downloading and review by customers.
The diagram in Figure 7 shows the SHCA steps in action.
Figure 7: SHCA steps
By integrating these steps, SHCA simplifies compliance management and helps enhance the overall security posture of AWS environments, aligning with the rigorous standards set by NIST SP 800-53 Rev. 5.
The following is a list of the artifacts that SHCA provides:
RMF-ready controls – Controls in full compliance (as per AWS Config) with AWS Operational Recommendations for NIST SP 800-53 Rev. 5, ready for direct import into RMF tools.
Controls needing attention – Controls not fully compliant with AWS Operational Recommendations for NIST SP 800-53 Rev. 5, indicating areas that require improvement.
Control compliance summary (CSV) – A detailed summary, in CSV format, of NIST SP 800-53 controls, including their compliance percentages and comprehensive narratives for each control.
Security Hub NIST 800-53 Analysis Summary – This automated report provides an executive summary of the current compliance posture, tailored for leadership reviews. It emphasizes urgent compliance concerns that require immediate action and guides the creation of a targeted remediation strategy for operational teams.
Original Security Hub findings – The raw JSON file from Security Hub, captured at the last time that the SHCA state machine ran.
User-friendly findings summary –A simplified, flattened version of the original findings, formatted for accessibility in common productivity tools.
As shown in Figure 8, the Security Hub NIST 800-53 Analysis Summary adopts an OpenSCAP-style format akin to Security Technical Implementation Guides (STIGs), which are grounded in the Department of Defense’s (DoD) policy and security protocols.
Organizations can use AWS security and compliance services to help maintain compliance with the NIST SP 800-53 standard. By implementing preventative IAM and SCP policies, organizations can restrict users from creating noncompliant resources. Detective controls such as Security Hub and Prowler can help identify misconfigurations, while proactive tools such as CloudFormation Guard can scan IaC to help prevent deployment of noncompliant resources. Finally, the Automated Security Response on AWS can automatically remediate findings to help resolve issues quickly. With this layered security approach across the organization, companies can verify that AWS deployments align to the NIST framework, simplify compliance reporting, and enable security teams to focus on critical issues. Get started on your continuous compliance journey today. Using AWS solutions, you can align deployments with the NIST 800-53 standard. Implement the tips in this post to help maintain continuous compliance.
In this post, we delve into the key aspects of using Amazon EMR for modern data management, covering topics such as data governance, data mesh deployment, and streamlined data discovery.
One of the key challenges in modern big data management is facilitating efficient data sharing and access control across multiple EMR clusters. Organizations have multiple Hive data warehouses across EMR clusters, where the metadata gets generated. To address this challenge, organizations can deploy a data mesh using AWS Lake Formation that connects the multiple EMR clusters. With the AWS Glue Data Catalog federation to external Hive metastore feature, you can now now apply data governance to the metadata residing across those EMR clusters and analyze them using AWS analytics services such as Amazon Athena, Amazon Redshift Spectrum, AWS Glue ETL (extract, transform, and load) jobs, EMR notebooks, EMR Serverless using Lake Formation for fine-grained access control, and Amazon SageMaker Studio. For detailed information on managing your Apache Hive metastore using Lake Formation permissions, refer to Query your Apache Hive metastore with AWS Lake Formation permissions.
In this post, we present a methodology for deploying a data mesh consisting of multiple Hive data warehouses across EMR clusters. This approach enables organizations to take advantage of the scalability and flexibility of EMR clusters while maintaining control and integrity of their data assets across the data mesh.
Use cases for Hive metastore federation for Amazon EMR
Hive metastore federation for Amazon EMR is applicable to the following use cases:
Governance of Amazon EMR-based data lakes – Producers generate data within their AWS accounts using an Amazon EMR-based data lake supported by EMRFS on Amazon Simple Storage Service (Amazon S3)and HBase. These data lakes require governance for access without the necessity of moving data to consumer accounts. The data resides on Amazon S3, which reduces the storage costs significantly.
Centralized catalog for published data – Multiple producers release data currently governed by their respective entities. For consumer access, a centralized catalog is necessary where producers can publish their data assets.
Consumer personas – Consumers include data analysts who run queries on the data lake, data scientists who prepare data for machine learning (ML) models and conduct exploratory analysis, as well as downstream systems that run batch jobs on the data within the data lake.
Cross-producer data access – Consumers may need to access data from multiple producers within the same catalog environment.
Data access entitlements – Data access entitlements involve implementing restrictions at the database, table, and column levels to provide appropriate data access control.
Solution overview
The following diagram shows how data from producers with their own Hive metastores (left) can be made available to consumers (right) using Lake Formation permissions enforced in a central governance account.
Producer and consumer are logical concepts used to indicate the production and consumption of data through a catalog. An entity can act both as a producer of data assets and as a consumer of data assets. The onboarding of producers is facilitated by sharing metadata, whereas the onboarding of consumers is based on granting permission to access this metadata.
The solution consists of multiple steps in the producer, catalog, and consumer accounts:
Deploy the AWS CloudFormation templates and set up the producer, central governance and catalog, and consumer accounts.
Test access to the producer cataloged Amazon S3 data using EMR Serverless in the consumer account.
Test access using Athena queries in the consumer account.
Test access using SageMaker Studio in the consumer account.
Producer
Producers create data within their AWS accounts using an Amazon EMR-based data lake and Amazon S3. Multiple producers then publish this data into a central catalog (data lake technology) account. Each producer account, along with the central catalog account, has either VPC peering or AWS Transit Gateway enabled to facilitate AWS Glue Data Catalog federation with the Hive metastore.
For each producer, an AWS Glue Hive metastore connector AWS Lambda function is deployed in the catalog account. This enables the Data Catalog to access Hive metastore information at runtime from the producer. The data lake locations (the S3 bucket location of the producers) are registered in the catalog account.
Central catalog
A catalog offers governed and secure data access to consumers. Federated databases are established within the catalog account’s Data Catalog using the Hive connection, managed by the catalog Lake Formation admin (LF-Admin). These federated databases in the catalog account are then shared by the data lake LF-Admin with the consumer LF-Admin of the external consumer account.
Data access entitlements are managed by applying access controls as needed at various levels, such as the database or table.
Consumer
The consumer LF-Admin grants the necessary permissions or restricted permissions to roles such as data analysts, data scientists, and downstream batch processing engine AWS Identity and Access Management (IAM) roles within its account.
Data access entitlements are managed by applying access control based on requirements at various levels, such as databases and tables.
Prerequisites
You need three AWS accounts with admin access to implement this solution. It is recommended to use test accounts. The producer account will host the EMR cluster and S3 buckets. The catalog account will host Lake Formation and AWS Glue. The consumer account will host EMR Serverless, Athena, and SageMaker notebooks.
Set up the producer account
Before you launch the CloudFormation stack, gather the following information from the catalog account:
Catalog AWS account ID (12-digit account ID)
Catalog VPC ID (for example, vpc-xxxxxxxx)
VPC CIDR (catalog account VPC CIDR; it should not overlap 10.0.0.0/16)
The VPC CIDR of the producer and catalog can’t overlap due to VPC peering and Transit Gateway requirements. The VPC CIDR should be a VPC from the catalog account where the AWS Glue metastore connector Lambda function will be eventually deployed.
The CloudFormation stack for the producer creates the following resources:
S3 bucket to host data for the Hive metastore of the EMR cluster.
VPC with the CIDR 10.0.0.0/16. Make sure there is no existing VPC with this CIDR in use.
VPC peering connection between the producer and catalog account.
A database and external tables, pointing to the downloaded sample data, in its Hive metastore.
Complete the following steps:
Launch the template PRODUCER.yml. It’s recommended to use an IAM role that has administrator privileges.
Gather the values for the following on the CloudFormation stack’s Outputs tab:
VpcPeeringConnectionId (for example, pcx-xxxxxxxxx)
DestinationCidrBlock (10.0.0.0/16)
S3ProducerDataLakeBucketName
Set up the catalog account
The CloudFormation stack for the catalog account creates the Lambda function for federation. Before you launch the template, on the Lake Formation console, add the IAM role and user deploying the stack as the data lake admin.
For the RouteTableId parameter, use the catalog account VPC RouteTableId. This is the VPC where the AWS Glue Hive metastore connector Lambda function will be deployed.
On the stack’s Outputs tab, copy the value for LFRegisterLocationServiceRole (arn:aws:iam::account-id: role/role-name).
Confirm if the Data Catalog setting has the IAM access control options un-checked and the current cross-account version is set to 4.
Log in to the producer account and add the following bucket policy to the producer S3 bucket that was created during the producer account setup. Add the ARN of LFRegisterLocationServiceRole to the Principal section and provide the S3 bucket name under the Resource section.
In the producer account, on the Amazon EMR console, navigate to the primary node EC2 instance to get the value for Private IP DNS name (IPv4 only) (for example, ip-xx-x-x-xx.us-west-1.compute.internal).
The default Region is set to us-east-1. Change it to your desired Region before deploying the function.
Use the VPC that was used as the CloudFormation input for the VPC CIDR. You can use the VPC’s default security group ID. If using another security group, make sure the outbound allows traffic to 0.0.0.0/0.
Next, you create a federated database in Lake Formation.
On the Lake Formation console, choose Data sharing in the navigation pane.
Choose Create database.
Provide the following information:
For Connection name, choose your connection.
For Database name, enter a name for your database.
For Database identifier, enter emrhms_salesdb (this is the database created on the EMR Hive metastore).
Choose Create database.
On the Databases page, select the database and on the Actions menu, choose Grant to grant describe permissions to the consumer account.
Under Principals, select External accounts and choose your account ARN.
Under LF-Tags or catalog resources, select Named Data Catalog resources and choose your database and table.
Under Table permissions, provide the following information:
For Table permissions¸ select Select and Describe.
For Grantable permissions¸ select Select and Describe.
Under Data permissions, select All data access.
Choose Grant.
On the Tables page, select your table and on the Actions menu, choose Grant to grant select and describe permissions.
Under Principals, select External accounts and choose your account ARN.
Under LF-Tags or catalog resources, select Named Data Catalog resources and choose your database.
Under Database permissions¸ provide the following information:
For Database permissions¸ select Create table and Describe.
For Grantable permissions¸ select Create table and Describe.
Choose Grant.
Set up the consumer account
Consumers include data analysts who run queries on the data lake, data scientists who prepare data for ML models and conduct exploratory analysis, as well as downstream systems that run batch jobs on the data within the data lake.
The consumer account setup in this section shows how you can query the shared Hive metastore data using Athena for the data analyst persona, EMR Serverless to run batch scripts, and SageMaker Studio for the data scientist to further use data in the downstream model building process.
For EMR Serverless and SageMaker Studio, if you’re using the default IAM service role, add the required Data Catalog and Lake Formation IAM permissions to the role and use Lake Formation to grant table permission access to the role’s ARN.
Data analyst use case
In this section, we demonstrate how a data analyst can query the Hive metastore data using Athena. Before you get started, on the Lake Formation console, add the IAM role or user deploying the CloudFormation stack as the data lake admin.
If the catalog and consumer accounts are not part of the organization in AWS Organizations, navigate to the AWS Resource Access Manager (AWS RAM) console and manually accept the resources shared from the catalog account.
On the Lake Formation console, on the Databases page, select your database and on the Actions menu, choose Create resource link.
Under Database resource link details, provide the following information:
For Resource link name, enter a name.
For Shared database’s region, choose a Region.
For Shared database, choose your database.
For Shared database’s owner ID, enter the account ID.
Choose Create.
Now you can use Athena to query the table on the consumer side, as shown in the following screenshot.
Batch job use case
Complete the following steps to set up EMR Serverless to run a sample Spark job to query the existing table:
On the Amazon EMR console, choose EMR Serverless in the navigation pane.
Choose Get started.
Choose Create and launch EMR Studio.
Under Application settings, provide the following information:
For Name, enter a name.
For Type, choose Spark.
For Release version, choose the current version.
For Architecture, select x86_64.
Under Application setup options, select Use custom settings.
Under Additional configurations, for Metastore configuration, select Use AWS Glue Data Catalog as metastore, then select Use Lake Formation for fine-grained access control.
Choose Create and start application.
On the application details page, on the Job runs tab, choose Submit job run.
Under Job details, provide the following information:
For Name, enter a name.
For Runtime role¸ choose Create new role.
Note the IAM role that gets created.
For Script location, enter the S3 bucket location created by the CloudFormation template (the script is emr-serverless-query-script.py).
Choose Submit job run.
Add the following AWS Glue access policy to the IAM role created in the previous step (provide your Region and the account ID of your catalog account):
On the Databases page, select the database and on the Actions menu, choose Grant to grant Lake Formation access to the EMR Serverless runtime role.
Under Principals, select IAM users and roles and choose your role.
Under LF-Tags or catalog resources, select Named Data Catalog resources and choose your database.
Under Resource link permissions, for Resource link permissions, select Describe.
Choose Grant.
On the Databases page, select the database and on the Actions menu, choose Grant on target.
Provide the following information:
Under Principals, select IAM users and roles and choose your role.
Under LF-Tags or catalog resources, select Named Data Catalog resources and choose your database and table
Under Table permissions, for Table permissions, select Select.
Under Data permissions, select All data access.
Choose Grant.
Submit the job again by cloning it.
When the job is complete, choose View logs.
The output should look like the following screenshot.
Data scientist use case
For this use case, a data scientist queries the data through SageMaker Studio. Complete the following steps:
Set up SageMaker Studio.
Confirm that the domain user role has been granted permission by Lake Formation to SELECT data from the table.
Follow steps similar to the batch run use case to grant access.
The following screenshot shows an example notebook.
Clean up
We recommend deleting the CloudFormation stack after use, because the deployed resources will incur costs. There are no prerequisites to delete the producer, catalog, and consumer CloudFormation stacks. To delete the Hive metastore connector stack on the catalog account (serverlessrepo-GlueDataCatalogFederation-HiveMetastore), first delete the federated database you created.
Conclusion
In this post, we explained how to create a federated Hive metastore for deploying a data mesh architecture with multiple Hive data warehouses across EMR clusters.
By using Data Catalog metadata federation, organizations can construct a sophisticated data architecture. This approach not only seamlessly extends your Hive data warehouse but also consolidates access control and fosters integration with various AWS analytics services. Through effective data governance and meticulous orchestration of the data mesh architecture, organizations can provide data integrity, regulatory compliance, and enhanced data sharing across EMR clusters.
We encourage you to check out the features of the AWS Glue Hive metastore federation connector and explore how to implement a data mesh architecture across multiple EMR clusters. To learn more and get started, refer to the following resources:
Sudipta Mitra is a Senior Data Architect for AWS, and passionate about helping customers to build modern data analytics applications by making innovative use of latest AWS services and their constantly evolving features. A pragmatic architect who works backwards from customer needs, making them comfortable with the proposed solution, helping achieve tangible business outcomes. His main areas of work are Data Mesh, Data Lake, Knowledge Graph, Data Security and Data Governance.
Deepak Sharma is a Senior Data Architect with the AWS Professional Services team, specializing in big data and analytics solutions. With extensive experience in designing and implementing scalable data architectures, he collaborates closely with enterprise customers to build robust data lakes and advanced analytical applications on the AWS platform.
Nanda Chinnappa is a Cloud Infrastructure Architect with AWS Professional Services at Amazon Web Services. Nanda specializes in Infrastructure Automation, Cloud Migration, Disaster Recovery and Databases which includes Amazon RDS and Amazon Aurora. He helps AWS Customer’s adopt AWS Cloud and realize their business outcome by executing cloud computing initiatives.
Operators, administrators, developers, and many other personas leveraging AWS come across multiple common issues when it comes to troubleshooting in the AWS Console. To help alleviate this burden, AWS released Amazon Q. Amazon Q is AWS’s generative AI-powered assistant that helps make your organizational data more accessible, write code, answer questions, generate content, solve problems, manage AWS resources, and take action. A component of Amazon Q is Amazon Q Developer. Amazon Q Developer reimagines your experience across the entire development lifecycle, including having the ability to help you understand errors and remediate them in the AWS Management Console. Additionally, Amazon Q also provides access to opening new AWS support cases to address your AWS questions if further troubleshooting help is needed.
In this blog post, we will highlight the five troubleshooting examples with Amazon Q. Specific use cases that will be covered include: EC2 SSH connection issues, VPC Network troubleshooting, IAM Permission troubleshooting, AWS Lambda troubleshooting, and troubleshooting S3 errors.
Prerequisites
To follow along with these examples, the following prerequisites are required:
In this section, we will show an example of troubleshooting an EC2 SSH connection issue. If you haven’t already, please be sure to create an Amazon EC2 instance for the purpose of this walkthrough.
First, sign into the AWS console and navigate to the us-west-2 region then click on the Amazon Q icon in the right sidebar on the AWS Management Console as shown below in figure 1.
Figure 1 – Opening Amazon Q chat in the console
With the Amazon Q chat open, we enter the following prompt below:
Prompt:
"Why cant I SSH into my EC2 instance <insert Instance ID here>?"
Note: you can obtain the instance ID from within EC2 service in the console.
We now get a response up stating: “It looks like you need help with network connectivity issues. Amazon Q works with VPC Reachability Analyzer to provide an interactive generative AI experience for troubleshooting network connectivity issues. You can try the preview experience here (available in US East N. Virginia Region).”
Now, Amazon Q will run an analysis for connectivity between the internet and your EC2 instance. Find a sample response from Amazon Q below:
Figure 3 – Response from Amazon Q network troubleshooting
Toward the end of the explanation from Amazon Q, it states that it checked the security groups for allowing inbound traffic from port 22 and was blocked from accessing.
Figure 4 – Response from Amazon Q network troubleshooting cont.
In this section, we will show how to troubleshoot a VPC network connection issue.
In this example, I have two EC2 instances, Server-1-demo and Server-2-demo in two separate VPCs shown below in figure 5. I want to leverage amazon Q troubleshooting to understand why these two instances cannot communicate with each other.
Figure 5 – two EC2 instances
First, we navigate to the AWS console and click on the Amazon Q icon in the right sidebar on the AWS Management Console as shown below in figure 1.
Figure 6 – Opening Amazon Q chat in the console
Now, with the Q console chat open, I enter the following prompt for Amazon Q below to help understand the connectivity issue between the servers:
Prompt:
"Why cant my Server-1-demo communicate with Server-2-demo?"
Figure 7 – prompt for Amazon Q connectivity troubleshooting
Now, click the preview experience here hyperlink to be redirected to the Amazon Q network troubleshooting – preview. Amazon Q troubleshooting will now generate a response as shown below in Figure 8.
Figure 8 – connectivity troubleshooting response generated by Amazon Q
In the response, Amazon Q states, “It sounds like you are troubleshooting connectivity between Server-1-demo and Server-2-demo. Based on the previous context, these instances are in different VPCs which could explain why TCP testing previously did not resolve the issue, if a peering connection is not established between the VPCs.“
So, we need to establish a VPC peering connection between the two instances since they are in different VPCs.
IAM Permission troubleshooting
Now, let’s take a look at how Amazon Q can help resolve IAM Permission issues.
In this example, I’m creating a cluster with Amazon Elastic Container Service (ECS). I chose to deploy my containers on Amazon EC2 instances, which prompted some configuration options, including whether I wanted an SSH Key pair. I chose to “Create a new key pair”.
Figure 9 – Configuring ECS key pair
That opens up a new tab in the EC2 console.
Figure 10 – Creating ECS key pair
But when I tried to create the SSH. I got the error below:
Figure 11 – ECS console error
So, I clicked the link to “Troubleshoot with Amazon Q” which revealed an explanation as to why my user was not able to create the SSH key pair and the specific permissions that were missing.
Figure 12 – Amazon Q troubleshooting analysis
So, I clicked the “Help me resolve” link ad I got the following steps.
Figure 13 – Amazon Q troubleshooting resolution
Even though my user had permissions to use Amazon ECS, the user also needs certain permission permissions in the Amazon EC2 services as well, specifically ec2:CreateKeyPair. By only enabling the specific action required for this IAM user, your organization can follow the best practice of least privilege.
Lambda troubleshooting
Another area Amazon Q can help is with AWS Lambda errors when doing development work in the AWS Console. Users may find issues with things like missing configurations, environment variables, and code typos. With Amazon Q, it can help you fix and troubleshoot these issues with step by step guidance on how to fix it.
In this example, in the us-west-2 region, we have created a new lambda function called demo_function_blog in the console with the Python 3.12 runtime. The following code below is included with a missing lambda layer for AWS pandas.
Lambda Code:
import json
import pandas as pd

def lambda_handler(event, context):
    data = {'Name': ['John', 'Jane', 'Jim'],'Age': [25, 30, 35]}
    df = pd.DataFrame(data)
    print(df.head()) # print first five rows

    return {
        'statusCode': 200,
        'body': json.dumps("execution successful!")
    }
Now, we configure a test event to test the following code within the lambda console called test-event as shown below in figure 14.
Figure 14 – configuring test event
Now that the test event is created, we can move over to the Test tab in the lambda console and click the Test button. We will then see an error (intended) and we will click on the Troubleshoot with Amazon Q button as shown below in figure 15.
Figure 15 – Lambda Error
Now we will be able to see Amazon Qs analysis of the issue. It states “It appears that the Lambda function is missing a dependency. The error message indicates that the function code requires the ‘pandas’ module, ….”. Click Help me resolve to get step by step instructions on the fix as shown below in figure 16.
Figure 16 – Amazon Q Analysis
Amazon Q will then generate a step-by-step resolution on how to the fix the error as shown below in figure 17.
Figure 17 – Amazon Q Resolution
Following with Amazon Q’s recommendations, we need to add a new lambda layer for the pandas dependency as shown below in figure 18:
Figure 18 – Updating lambda layer
Once updated, go to the Test tab once again and click Test. The function code should now run successfully as shown below in figure 19:
While working with Amazon S3, users might encounter errors that can disrupt the smooth functioning of their operations. Identifying and resolving these issues promptly is crucial for ensuring uninterrupted access to S3 resources. Amazon Q, a powerful tool, offers a seamless way to troubleshoot errors across various AWS services, including Amazon S3.
In this example we use Q to troubleshoot S3 Replication rule configuration error. Imagine you’re attempting to configure a replication rule for an Amazon S3 bucket, and configuration fails. You can turn to Amazon Q for assistance. If you receive an error that Amazon Q can help with, a Troubleshoot with Amazon Q button appears in the error message. Navigate to the Amazon S3 service in the console to follow along with this example if it applies to your use case.
Figure 20 – S3 console error
To use Amazon Q to troubleshoot, choose Troubleshoot with Amazon Q to proceed. A window appears where Amazon Q provides information about the error titled “Analysis“.
Amazon Q diagnosed that the error occurred because versioning is not enabled for the source bucket specified. Versioning must be enabled on the source bucket in order to replicate objects from that bucket.
Amazon Q also provides an overview on how to resolve this error. To see detailed steps for how to resolve the error, choose Help me resolve.
Figure 21 – Amazon Q analysis
It can take several seconds for Amazon Q to generate instructions. After they appear, follow the instructions to resolve the error.
Figure 22 – Amazon Q Resolution
Here, Amazon Q recommends the following steps to resolve the error:
Navigate to the S3 console
Select the S3 bucket
Go to the Properties tab
Under Versioning, click Edit
Enable versioning on the bucket
Return to replication rule creation page
Retry creating replication rule
Conclusion
Amazon Q is a powerful AI-powered assistant that can greatly simplify troubleshooting of common issues across various AWS services, especially for Developers. Amazon Q provides detailed analysis and step-by-step guidance to resolve errors efficiently. By leveraging Amazon Q, AWS users can save significant time and effort in diagnosing and fixing problems, allowing them to focus more on building and innovating with AWS. Amazon Q represents a valuable addition to the AWS ecosystem, empowering users with enhanced support and streamlined troubleshooting capabilities.
As a developer, marketing professional, or someone in the communications space, you’re likely familiar with the importance of SMS messaging in engaging customers and driving valuable interactions. However, you may have also encountered the growing challenge of artificially inflated traffic (AIT), also known as SMS pumping. A new report co-authored by Enea revealed that AIT is so widespread within the SMS ecosystem that 19.8B-35.7B fraudulent messages were sent by bad actors in 2023, incurring substantial costs of over $1 billion. In this blog post, we’ll explore how you can use Protect configurations, a powerful set of capabilities within Amazon Pinpoint SMS, that provides granular control over which destination countries your SMS, MMS, and voice messages can be sent to.
” width=”1252″ height=”889″>
What is SMS Pumping, aka Artificially Inflated Traffic (AIT)?
AIT, or SMS pumping, is a type of fraud where bad actors use bots to generate large volumes of fake SMS traffic. These bots target businesses’ whose websites, apps, and other assets have forms or other mechanisms that trigger SMS being sent out. Common use cases for SMS such as one-time passwords (OTPs), app download links, promotion signups, etc. are all targets for these bad actors to “pump” SMS and send out fraudulent messages. The goal is to artificially inflate the number of SMS messages a business sends, resulting in increased costs and a negative impact on the sender’s reputation. In the realm of SMS-based artificially inflated traffic (AIT), the prevalent method for bad actors to profit involves colluding with parties in the SMS delivery chain to receive a portion of the revenue generated from each fraudulent message sent.
” width=”1280″ height=”720″>
AIT poses several challenges for businesses:
Overspending: The fake SMS traffic generated by AIT bots results in businesses paying for messages that yield no actual results.
Interrupted service: Large volumes of AIT can force businesses to temporarily halt SMS services, disrupting legitimate customer communications.
Diverted focus: Dealing with AIT can shift businesses’ attention away from core operations and priorities.
Reduced deliverability rates due to the messages never being interacted with and/or large volumes of SMS being sent quickly.
How does Protect mitigate AIT?
Amazon Pinpoint’s Protect feature allows you to control which countries you can send messages to. This is beneficial if your customers are located in specific countries.
With Protect, you can create a list of country rules that either allow or block messages to each destination country. These country rules can be applied to SMS, MMS, and voice messages sent from your AWS account. The Protect configurations you create enable precise control over which destination countries your messages can be sent to. This helps mitigate the impact of AIT by allowing you to tailor where you do or do not send.
Protect offers flexibility in how the country rules are applied. You can apply them at the account level, the configuration set level, or the individual message level. This enables you to customize your AIT mitigation strategy to best fit your business needs and messaging patterns.
By leveraging Protect within Amazon Pinpoint, you can help ensure the integrity and cost-effectiveness of your SMS, MMS, and voice communications.
Account-level Protect Configuration
The simplest approach is to create a Protect configuration and associate it as the account default. This means the allow/block rules defined in that configuration will be applied across all messages sent from your account, unless overridden. This is an effective option if you only need one set of country rules applied universally.
Configuration set-specific Protect configuration
You can associate a Protect configuration with one or more of your Pinpoint SMS configuration sets. This allows you to apply different country rules to distinct messaging flows or use cases within your application without changing your existing code if you are already using Config Sets. It also enables more detailed logging and monitoring of the Protect configuration’s impact, such as:
Error Logs: Logging of any errors or issues encountered when messages are sent, providing insights into how the Protect configuration is affecting message delivery.
Audit Logs: Records of all configuration changes, access attempts, and other relevant activities related to the Protect configuration, allowing for comprehensive auditing and monitoring.
Usage Metrics: Tracking of usage statistics, such as the number of messages sent to different countries, the impact of the Protect configuration on message volumes, and other usage-related data.
Compliance and Policy Enforcement Logs: Documentation of how the Protect configuration is enforcing compliance with messaging policies and regulations, including any instances where messages are blocked or allowed based on the configuration rules.
Dynamic Protect configuration per message
If your needs are even more specific, you can create a Protect configuration without any association, and then specify its ID when sending messages via the Pinpoint APIs (e.g. SendMediaMessage, SendTextMessage, SendVoiceMessage). This gives you the ability to dynamically choose the Protect configuration to apply for each individual message, providing the ultimate flexibility.
Regardless of the approach, the core benefit of Protect configurations is the ability to precisely control which destination countries your messages may be sent to. Blocking countries where you don’t have a presence or where SMS pricing is high eliminates your exposure to fraudulent AIT traffic originating from those regions. This helps protect your messaging budget, maintain service continuity, and focus your efforts on legitimate customer interactions.
Who should use Protect configurations?
Protect configurations are designed to benefit a wide range of AWS customers, particularly those who:
Send SMS messages to a limited number of countries: If your business primarily operates in a few specific countries, Protect configurations can help you easily block SMS messages to countries where you don’t have a presence, reducing the risk of AIT.
Have experienced AIT issues in the past: If your business has been a target of SMS pumping, Protect configurations can help you regain control over your SMS communications and prevent future AIT attacks.
Want to proactively protect their SMS messaging: Even if you haven’t encountered AIT issues yet, Protect configurations can help you stay ahead of the curve and maintain the integrity of your SMS communications.
How to create a country rules list with Protect configuration
To begin building a list of country rules that allow or block messages to specific destination countries, you start by creating a new Protect configuration. There are two ways to accomplish this, either by using the console, or the API.
Option 1 – Using the AWS Console
Console Scenario:My account is out of the sandbox and I only want to send to 1 country – United Kingdom (iso:GB) using the SenderID “DEMOTP”.
At a high level, we will follow the three steps outlined below for each method. In our examples, we used a SenderID as our Originator. However, it should be noted that the same process can be achieved using any originator you’d like. i.e. SenderID, Phone pool, Phone number, 10DLC, short code, etc.
Create SenderID (Optional if you already have one)
Select all countries by toggling checkbox in search bar
” width=”863″ height=”521″>
Search for Country=United Kingdom then deselect United Kingdom
” width=”865″ height=”582″>
Set as Account Default and select Create protect configuration
” width=”1497″ height=”1173″>
3) Send a test message with SMS simulator
Note: The Pinpoint SMS Simulator provides special phone numbers you can use to send test text messages and receive realistic event records, all within the confines of the Amazon Pinpoint service. These simulator phone numbers are designed to stay entirely within the Pinpoint SMS ecosystem, ensuring your test messages don’t get sent over the carrier network.
You can use these simulator phone numbers to send both SMS and MMS messages, allowing you to thoroughly validate your message content, workflow, and event handling. The responses you receive back will mimic either success or fail depending on which destination simulator number you send to.
For Originator, Choose Sender ID, and select your Sender ID created from earlier.
Under Destination number, select Simulator numbers and choose United Kingdom (GB). Enter a test message in the Message body.
Finally, choose send test message. This should prompt a green “Success” banner at the top of your page.
” width=”1336″ height=”1313″>
Conversely, follow the previous test message steps, and instead attempt to send to anywhere other than the United Kingdom (GB). In this example, Australia (AU)
As shown below in the screenshot this one is blocked since you have configured to only send to GB.
” width=”1333″ height=”1364″>
Option 2 – Using the V2 API and CLI
V2 API Scenario: My account is out of the sandbox and I want to BLOCK only 1 country – Australia (AU) while using the SenderID “DEMOTP”.
1) Create SenderID for GB
Note: before using the CLI remember to configure your access and secret key using
aws configure
Windows users should use PowerShell over cmd to test
Use RequestSenderId to create the same Sender Id as previously made via the console.
{
An error occurred (ConflictException) when calling the
SendTextMessage operation: Conflict Occurred -
Reason="DESTINATION_COUNTRY_BLOCKED_BY_PROTECT_CONFIGURATION" ResourceType="protect-configuration" ResourceId="string"
}
Conclusion
As SMS messaging continues to play a crucial role in customer engagement and authentication, protecting your communications from AIT is more important than ever. Amazon Pinpoint Protect provides a powerful and user-friendly solution to help you mitigate the impact of SMS pumping, ensuring the integrity of your SMS channels and preserving your business’ reputation and resources. Whether you’re a small business or a large enterprise, Pinpoint Protect is a valuable tool to have in your arsenal as you navigate the evolving landscape of SMS messaging.
To get started with Pinpoint SMS Protect, visit the Amazon Pinpoint SMS documentation or reach out to your AWS account team. And don’t forget to let us know in the comments how Protect configurations has helped you combat AIT and strengthen your SMS communications.
A few resources to help you plan for your SMS program:
The V2 API for SMS and Voice has many more useful actions not possible with the V1 API so we encourage you to explore how it can further help you simplify and automate your applications.
Brett Ezell is your friendly neighborhood Solutions Architect at AWS, where he specializes in helping customers optimize their SMS and email campaigns using Amazon Pinpoint and Amazon Simple Email Service. As a former US Navy veteran, Brett brings a unique perspective to his work, ensuring customers receive tailored solutions to meet their needs. In his free time, Brett enjoys live music, collecting vinyl, and the challenges of a good workout. And, as a self-proclaimed comic book aficionado, he can often be found combing through his local shop for new books to add to his collection.
Genomics workflows process petabyte-scale datasets on large pools of compute resources. In this blog post, we discuss how life science organizations can use Amazon Web Services (AWS) to run transcriptomic sequencing data analysis using public datasets. This allows users to quickly test research hypotheses against larger datasets in support of clinical diagnostics. We use AWS HealthOmics and AWS Step Functions to orchestrate the entire lifecycle of preparing and analyzing sequence data and remove the associated heavy lifting.
Use case
In genomics, transcription relates to the process of making a ribonucleic acid (RNA) copy from a gene’s deoxyribonucleic acid (DNA). Usually, RNA is single-stranded, although some RNA viruses are double-stranded. With RNA sequencing (RNA-Seq), scientists isolate the RNA, prepare an RNA library, and use next-generation sequencing technology to decode it. Organizations around the world use RNA-Seq to support clinical diagnostics.
In our use case, life science research teams use workflows written in Nextflow to process RNA-Seq datasets in FASTQ file format. Following their initial RNA-Seq studies on internal datasets, scientists can extend their insights by using public datasets. For example, the Gene Expression Omnibus (GEO) functional genomics data repository is hosted by the National Center for Biotechnology Information (NCBI) and offers multiple download options and formats. Scientists can download datasets in FASTQ format from GEO File Transfer Protocol (FTP) and compress them into the .gz format before further analysis.
Scaling and automating the data ingestion can be challenging. For example, scientists might need to do the following:
Manually download FASTQ files and invoke their analysis pipelines
Monitor the workflow runs, which can span hours, days, or weeks
Manage the infrastructure for performance and scale
This blog post presents a solution that removes this undifferentiated heavy lifting.
Prerequisites
To build this solution, you must be analyzing transcriptomic sequencing data with the Nextflow workflow system and make use of GEO FASTQ datasets. In addition, you must do the following:
Create one Amazon DynamoDB table to track the status of data ingestion. This helps with checkpointing and avoids repetitive ingestion jobs so that you can keep data ingestion cost to a minimum.
Solution overview
Using AWS, you can automate the entire RNA-Seq Nextflow pipeline. Users only need to provide the GEO IDs, then the pipeline ingests the corresponding FASTQ sample files and performs the subsequent data analysis.
Our solution, shown in Figure 1, uses a combination of AWS HealthOmics and AWS Step Functions. HealthOmics manages the compute, scalability, scheduling, and orchestration required for processing large RNA-Seq datasets. This helps scientists focus on writing their pipelines in Nextflow while AWS takes care of the underlying infrastructure. Step Functions adds reliability to the workflow from dataset ingestion to output archival. Automating the entire workflow also helps with tracing specific invocations and troubleshooting errors.
Figure 1. RNA sequencing using HealthOmics
Our solution includes the following:
The scientist creates and uploads a CSV file to the GEO metadata S3 bucket. The CSV file includes a reference to the specific GEO ID that is ingested. An Amazon S3 Event Notification configured on s3:ObjectCreated events (in this case, the CSV file upload) invokes an AWS Lambda function.
The Lambda function first extracts the corresponding Sequence Read Run (SRR) IDs of the GEO ID. Next, it starts a Step Functions state machine with the following input parameters: the SRR IDs, species of the samples, and GEO ID. The state machine uses an AWS Batch job queue for parallel ingestion.
The Lambda function writes the following metadata to a DynamoDB table for future reference:
Ingested GEO ID and corresponding list of SRR IDs
Amazon S3 output paths to the ingested FASTQ files
Overall workflow status
Ingested species
Upon ingestion completion, the state machine puts the RNA-Seq sample sheet into the FASTQ S3 bucket. This invokes a Lambda function, which launches the RNA-Seq analysis workflow with the following input parameters:
Sample sheet
GEO ID
Other relevant metadata
Our RNA-Seq data analysis is run with HealthOmics and the associated sequence store. We use Step Functions to launch this workflow and ingest the relevant files to the sequence store.
Upon workflow completion, HealthOmics writes the output data (BAM files) to the output S3 bucket.
Implementation considerations
Dataset preparation
The Step Functions state machine orchestrates the ingestion of FASTQ files through the following steps:
The state machine invokes the Map state in Step Functions that uses dynamic parallelism for increased scale, with the SRR IDs array as input. You can now launch multiple AWS Batch jobs in parallel to ingest the FASTQ files that correspond to the SRR ID input.
The state machine checks our ingestion DynamoDB table to see if the corresponding SRR ID has already been processed and has ingested the corresponding FASTQ files. If the SRR ID ingested the files, the state machine writes the sample sheet to the FASTQ S3 bucket and terminates successfully.
The state machine uses the NCBI-provided sra-tools Docker container and fasterq-dump command to ingest the FASTQ files. The state machine generates the set of ingestion commands and starts the AWS Batch job. The ingestion commands are a set of shell commands that interact with NCBI for downloading FASTQ files. These commands compress the files with pigz, and then uploads them to an S3 bucket.
The state machine updates the DynamoDB table with the ingestion status.
If the ingestion is successful, then the state machine continues to step 5.
If the ingestion isn’t successful, the state machine writes a message to Amazon Simple Notification Service (Amazon SNS) to notify scientists of the failure.
A Lambda function generates the RNA-Seq sample sheet with the combined samples to analyze. This sample sheet is a CSV file containing:
The paths to the ingested FASTQ files.
The names of each corresponding SRR ID as input to the RNA-Seq workflow.
The state machine notifies that the ingestion job is complete by publishing a message to an Amazon SNS topic before terminating itself.
Figure 2 provides a detailed overview of the state machine.
Figure 2. RNA sequencing data ingestion
Dataset analysis
A Lambda function divides the RNA-Seq sample sheet in compliance with the Step Functions service quota. This enables parallel processing using a Map state.
Our transcriptomic analysis workflow does the following:
Checks if samples are single-end (one FASTQ file per sample) or paired-end (two sets of FASTQ files per sample).
In parallel, a Lambda function initiates the HealthOmics RNA-Seq workflow.
Upon successful completion, HealthOmics stores the output data in Amazon S3. Finally, our state machine imports the output BAM files into the HealthOmics sequence store for future use.
Figure 3 provides a detailed overview of our state machine.
Figure 3. RNA sequencing workflow
Cleanup (optional)
Delete all AWS resources that you no longer want to maintain.
Conclusion
HealthOmics removes the heavy lifting associated with gaining insights from genomics, transcriptomics, and other omics data. We used RNA-Seq analysis to showcase an example scientific workflow that can benefit from HealthOmics. When using HealthOmics in combination with Step Functions, scientists can automate the entire workflow from initial dataset preparation to archival. To learn more, we encourage you to explore our HealthOmics tutorials on GitHub.
Amazon Kinesis Data Streams is used by many customers to capture, process, and store data streams at any scale. This level of unparalleled scale is enabled by dividing each data stream into multiple shards. Each shard in a stream has a 1 Mbps or 1,000 records per second write throughput limit. Whether your data streaming application is collecting clickstream data from a web application or recording telemetry data from billions of Internet of Things (IoT) devices, streaming applications are highly susceptible to a varying amount of data ingestion. Sometimes such a large and unexpected volume of data could be the thing we least expect. For instance, consider application logic with a retry mechanism when writing records to a Kinesis data stream. In case of a network failure, it’s common to buffer data locally and write them when connectivity is restored. Depending on the rate that data is buffered and the duration of connectivity issue, the local buffer can accumulate enough data that could saturate the available write throughput quota of a Kinesis data stream.
When an application attempts to write more data than what is allowed, it will receive write throughput exceeded errors. In some instances, not being able to address these errors in a timely manner can result in data loss, unhappy customers, and other undesirable outcomes. In this post, we explore the typical reasons behind write throughput exceeded errors, along with methods to identify them. We then guide you on swift responses to these events and provide several solutions for mitigation. Lastly, we delve into how on-demand capacity mode can be valuable in addressing these errors.
Why do we get write throughput exceeded errors?
Write throughput exceeded errors are generally caused by three different scenarios:
The simplest is the case where the producer application is generating more data than the throughput available in the Kinesis data stream (the sum of all shards).
Next, we have the case where data distribution is not even across all shards, known as hot shard issue.
Write throughout errors can also be caused by an application choosing a partition key to write records at a rate exceeding the throughput offered by a single shard. This situation is somewhat similar to hot shard issue, but as we see later in this post, unlike a hot shard issue, you can’t solve this problem by adding more shards to the data stream. This behavior is commonly known as a hot key issue.
Before we discuss how to diagnose these issues, let’s look at how Kinesis data streams organize data and its relationship to write throughput exceeded errors.
A Kinesis data stream has one or more shards to store data. Each shard is assigned a key range in 128-bit integer space. If you view the details of a data stream using the describe-stream operation in the AWS Command Line Interface (AWS CLI), you can actually see this key range assignment:
When a producer application invokes the PutRecord or PutRecords API, the service calculates a MD5 hash for the PartitionKey specified in the record. The resulting hash is used to determine which shard to store that record. You can take more control over this process by setting the ExplicitHashKey property in the PutRecord request to a hash key that falls within a specific shard’s key range. For instance, setting ExplicitHashKey to 0 will guarantee that record is written to shard ID shardId-0 in the stream described in the preceding code snippet.
How partition keys are distributed across available shards plays a vital role in maximizing the available throughput in a Kinesis data stream. When the partition key being used is repeated frequently in a way that some keys are more frequent than the others, shards storing those records will be utilized more. We also get the same net effect if we use ExplicitHashKey and our logic for choosing the hash key is biased towards a subset of shards.
Imagine you have a fleet of web servers logging performance metrics for each web request served into a Kinesis data stream with two shards and you used a request URL as the partition key. Each time a request is served, the application makes a call to the PutRecord API carrying a 10-bytes record. Let’s say that you have a total of 10 URLs and each receives 10 requests per second. Under these circumstances, total throughput required for the workload is 1,000 bytes per second and 100 requests per second. If we assume perfect distribution of 10 URLs across the two shards, each shard will receive 500 bytes per second and 50 requests per second.
Now imagine one of these URLs went viral and it started receiving 1,000 requests per second. Although the situation is positive from a business point of view, you’re now on the brink of making users unhappy. After the page gained popularity, you’re now counting 1,040 requests per second for the shard storing the popular URL (1000 + 10 * 4). At this point, you’ll receive write throughput exceeded errors from that shard. You’re throttled based on the requests per second quota because even with increased requests, you’re still generating approximately 11 KB of data.
You can solve this problem either by using a UUID for each request as the partition key so that you share the total load across both shards, or by adding more shards to the Kinesis data stream. The method you choose depends on how you want to consume data. Changing the partition key to a UUID would be problematic if you want performance metrics from a given URL to be always processed by the same consumer instance or if you want to maintain the order of records on a per-URL basis.
Knowing the exact cause of write throughout exceeded errors is an important step in remediating them. In the next sections, we discuss how to identify the root cause and remediate this problem.
Identifying the cause of write throughput exceeded errors
Let’s look at a few tests we performed in a stream with two shards to illustrate various scenarios. In this instance, with two shards in our stream, total throughput available to our producer application is either 2 Mbps or 2,000 records per second.
In the first test, we ran a producer to write batches of 30 records, each being 100 KB, using the PutRecords API. As you can see in the graph on the left of the following figure, our WriteProvisionedThroughputExceedded errors count went up. The graph on the right shows that we are reaching the 2 Mbps limit, but our incoming records rate is much lower than the 2,000 records per second limit (Kinesis metrics are published at 1-minute intervals, hence 125.8 and 120,000 as upper limits).
The following figures show how the same three metrics changed when we changed the producer to write batches of 500 records, each being 50 bytes, in the second test. This time, we exceeded the 2,000 records per second throughput limit, but our incoming bytes rate is well under the limit.
Now that we know that problem exists, we should look for clues to see if we’re exceeding the overall throughput available in the stream or if we’re having a hot shard issue due to an imbalanced partition key distribution as discussed earlier. One approach to this is to use enhanced shard-level metrics. Prior to our tests, we enabled enhanced shard-level metrics, and we can see in the following figure that both shards equally reached their quota in our first test.
We have seen Kinesis data streams containing thousands of shards harnessing the power of infinite scale in Kinesis data streams. However, plotting enhanced shard-level metrics on a such large stream may not provide an easy to way to find out which shards are over-utilized. In that instance, it’s better to use CloudWatch Metrics Insights to run queries to view top-n items, as shown in the following code (adjust the LIMIT 5 clause accordingly):
-- Show top 5 shards with highest incoming bytes
SELECT
SUM(IncomingBytes)
FROM "AWS/Kinesis"
GROUP BY ShardId, StreamName
ORDER BY MAX() DESC
LIMIT 5

-- Show top 5 shards with highest incoming records
SELECT
SUM(IncomingRecords)
FROM "AWS/Kinesis"
GROUP BY ShardId, StreamName
ORDER BY MAX() DESC
LIMIT 5
Enhanced shard-level metrics are not enabled by default. If you didn’t enable them and you want to perform root cause analysis after an incident, this option isn’t very helpful. In addition, you can only query the most recent 3 hours of data. Enhanced shard-level metrics also incur additional costs for CloudWatch metrics and it may be cost prohibitive to have it always on in data streams with a lot of shards.
One interesting scenario is when the workload is bursty, which can make the resulting CloudWatch metrics graphs rather baffling. This is because Kinesis publishes CloudWatch metric data aggregated at 1-minute intervals. Consequently, although you can see write throughput exceeded errors, your incoming bytes/records graphs may be still within the limits. To illustrate this scenario, we changed our test to create a burst of writes exceeding the limits and then sleep for a few seconds. Then we repeated this cycle for several minutes to yield the graphs in the following figure, which show write throughput exceeded errors on the left, but the IncomingBytes and IncomingRecords graphs on the right seem fine.
To enhance the process of identifying write throughput exceeded errors, we developed a CLI tool called Kinesis Hot Shard Advisor (KHS). With KHS, you can view shard utilization when shard-level metrics are not enabled. This is particularly useful for investigating an issue retrospectively. It can also show most frequently written keys to a particular shard. KHS reports shard utilization by reading records and aggregating them per second intervals based on the ApproximateArrivalTimestamp in the record. Because of this, you can also understand shard utilization drivers during bursty write workloads.
By running the following command, we can get KHS to inspect the data that arrived in 1 minute during our first test and generate a report:
For the given time window, the summary section in the generated report shows the maximum bytes per second rate observed, total bytes ingested, maximum records per second observed, and the total number of records ingested for each shard.
Choosing a shard ID in the first column will display a graph of incoming bytes and records for that shard. This is similar to the graph you get in CloudWatch metrics, except the KHS graph reports on a per-second basis. For instance, in the following figure, we can see how the producer was going through a series of bursty writes followed by a throttling event during our test case.
Running the same command with the -aggregate-key option enables partition key distribution analysis. It generates an additional graph for each shard showing the key distribution, as shown in the following figure. For our test scenario, we can only see each key being used one time because we used a new UUID for each record.
Because KHS reports based on data stored in streams, it creates an enhanced fan-out consumer at startup to prevent using the read throughput quota available for other consumers. When the analysis is complete, it deletes that enhanced fan-out consumer.
Due its nature of reading data streams, KHS can transfer a lot of data during analysis. For instance, assume you have a stream with 100 shards. If all of them are fully utilized during a minute window specified using -from and -to arguments, the host running KHS will receive at least 1 MB * 100 * 60 = 6000 MB = approximately 6 GB data. To avoid this kind of excessive data transfer and speed up the analysis process, we recommend first using the WriteProvisionedThroughoutExceeded CloudWatch metric to identify a time period when you experienced throttling and use a small window (such as 10 seconds) with KHS. You can also run KHS in an Amazon Elastic Compute Cloud (Amazon EC2) instance in the same AWS Region as your Kinesis data stream to minimize network latency during reads.
KHS is designed to run in a single machine to diagnose large-scale workloads. Using a naive in-memory-based counting algorithm (such as a hash map storing the partition key and count) for partition key distribution analysis could easily exhaust the available memory in the host system. Therefore, we use a probabilistic data structure called count-min-sketch to estimate the number of times a key has been used. As a result, the number you see in the report should be taken as an approximate value rather than an absolute value. After all, with this report, we just want to find out if there’s an imbalance in the keys written to a shard.
Now that we understand what causes hot shards and how to identify them, let’s look at how to deal with this in producer applications and remediation steps.
Remediation steps
Having producers retry writes is a step towards making our producers resilient to write throughput exceeded errors. Consider our earlier sample application logging performance metrics data for each web request served by a fleet of web servers. When implementing this retry mechanism, you should remember that records that are not written to the Kinesis stream are going to be in host system’s memory. The first issue with this is, if the host crashes before the records could be written, you’ll experience data loss. Scenarios such as tracking web request performance data might be more forgiving for this type of data loss than scenarios like financial transactions. You should evaluate durability guarantees required for your application and employ techniques to achieve them.
The second issue is that records waiting to be written to the Kinesis data stream are going to consume the host system’s memory. When you start getting throttled and have some retry logic in place, you should notice that your memory utilization is going up. A retry mechanism should have a way to avoid exhausting the host system’s memory.
With the appropriate retry logic in place, if you receive write throughput exceeded errors, you can use the methods we discussed earlier to identify the cause. After you identify the root cause, you can choose the appropriate remediation step:
If the producer application is exceeding the overall stream’s throughput, you can add more shards to the stream to increase its write throughput capacity. When adding shards, the Kinesis data stream makes the new shards available incrementally, minimizing the time that producers experience write throughput exceeded errors. To add shards to a stream, you can use the Kinesis console, the update-shard-count operation in the AWS CLI, the UpdateShardCount API through the AWS SDK, or the ShardCount property in the AWS CloudFormation template used to create the stream.
If the producer application is exceeding the throughput limit of some shards (hot shard issue), pick one of the following options based on consumer requirements:
If locality of data is required (records with the same partition key are always processed by the same consumer) or an order based on partition key is required, use the split-shard operation in the AWS CLI or the SplitShard API in the AWS SDK to split those shards.
If locality or order based on the current partition key is not required, change the partition key scheme to increase its distribution.
If the producer application is exceeding the throughput limit of a shard due to a single partition key (hot key issue), change the partition key scheme to increase its distribution.
Kinesis Data Streams also has an on-demand capacity mode. In on-demand capacity mode, Kinesis Data Streams automatically scales streams when needed. Additionally, you can switch between on-demand and provisioned capacity modes without causing an outage. This could be particularly useful when you’re experiencing write throughput exceeded errors but require immediate reaction to keep your application available to your users. In such instances, you can switch a provisioned capacity mode data stream to an on-demand data stream and let Kinesis Data Streams handle the required scale appropriately. You can then perform root cause analysis in the background and take corrective actions. Finally, if necessary, you can change the capacity mode back to provisioned.
Conclusion
You should now have a solid understanding of the common causes of write throughput exceeded errors in Kinesis data streams, how to diagnose them, and what actions to take to appropriately deal with them. We hope that this post will help you make your Kinesis Data Streams applications more robust. If you are just starting with Kinesis Data Streams, we recommend referring to the Developer Guide.
If you have any questions or feedback, please leave them in the comments section.
About the Authors
Buddhike de Silva is a Senior Specialist Solutions Architect at Amazon Web Services. Buddhike helps customers run large scale streaming analytics workloads on AWS and make the best out of their cloud journey.
Nihar Sheth is a Senior Product Manager at Amazon Web Services. He is passionate about developing intuitive product experiences that solve complex customer problems and enable customers to achieve their business goals.
Designing a full stack search application requires addressing numerous challenges to provide a smooth and effective user experience. This encompasses tasks such as integrating diverse data from various sources with distinct formats and structures, optimizing the user experience for performance and security, providing multilingual support, and optimizing for cost, operations, and reliability.
Amazon OpenSearch Serverless is a powerful and scalable search and analytics engine that can significantly contribute to the development of search applications. It allows you to store, search, and analyze large volumes of data in real time, offering scalability, real-time capabilities, security, and integration with other AWS services. With OpenSearch Serverless, you can search and analyze a large volume of data without having to worry about the underlying infrastructure and data management. An OpenSearch Serverless collection is a group of OpenSearch indexes that work together to support a specific workload or use case. Collections have the same kind of high-capacity, distributed, and highly available storage volume that’s used by provisioned Amazon OpenSearch Service domains, but they remove complexity because they don’t require manual configuration and tuning. Each collection that you create is protected with encryption of data at rest, a security feature that helps prevent unauthorized access to your data. OpenSearch Serverless also supports OpenSearch Dashboards, which provides an intuitive interface for analyzing data.
OpenSearch Serverless supports three primary use cases:
Time series – The log analytics workloads that focus on analyzing large volumes of semi-structured, machine-generated data in real time for operational, security, user behavior, and business insights
Search – Full-text search that powers applications in your internal networks (content management systems, legal documents) and internet-facing applications, such as ecommerce website search and content search
Vector search – Semantic search on vector embeddings that simplifies vector data management and powers machine learning (ML) augmented search experiences and generative artificial intelligence (AI) applications, such as chatbots, personal assistants, and fraud detection
In this post, we walk you through a reference implementation of a full-stack cloud-centered serverless text search application designed to run using OpenSearch Serverless.
Solution overview
The following services are used in the solution:
AWS Amplify is a set of purpose-built tools and features that enables frontend web and mobile developers to quickly and effortlessly build full-stack applications on AWS. These tools have the flexibility to use the breadth of AWS services as your use cases evolve. This solution uses the Amplify CLI to build the serverless movie search web application. The Amplify backend is used to create resources such as the Amazon Cognito user pool, API Gateway, Lambda function, and Amazon S3 storage.
Amazon API Gateway is a fully managed service that makes it straightforward for developers to create, publish, maintain, monitor, and secure APIs at any scale. We use API Gateway as a “front door” for the movie search application for searching movies.
AWS CloudFront accelerates the delivery of web content such as static and dynamic web pages, video streams, and APIs to users across the globe by caching content at edge locations closer to the end-users. This solution uses CloudFront with Amazon S3 to deliver the search application user interface to the end users.
Amazon Cognito makes it straightforward for adding authentication, user management, and data synchronization without having to write backend code or manage any infrastructure. We use Amazon Cognito for creating a user pool so the end-user can log in to the movie search application through Amazon Cognito.
AWS Lambda is a serverless, event-driven compute service that lets you run code for virtually any type of application or backend service without provisioning or managing servers. Our solution uses a Lambda function to query OpenSearch Serverless. API Gateway forwards all requests to the Lambda function to serve up the requests.
Amazon OpenSearch Serverless is a serverless option for OpenSearch Service. In this post, you use common methods for searching documents in OpenSearch Service that improve the search experience, such as request body searches using domain-specific language (DSL) for queries. The query DSL lets you specify the full range of OpenSearch search options, including pagination and sorting the search results. Pagination and sorting are implemented on the server side using DSL as part of this implementation.
Amazon Simple Storage Service (Amazon S3) is an object storage service that offers industry-leading scalability, data availability, security, and performance. The solution uses Amazon S3 as storage for storing movie trailers.
AWS WAF helps protects web applications from attacks by allowing you to configure rules that allow, block, or monitor (count) web requests based on conditions that you define. We use AWS WAF to allow access to the movie search app from only IP addresses on an allow list.
The following diagram illustrates the solution architecture.
The workflow includes the following steps:
The end-user accesses the CloudFront and Amazon S3 hosted movie search web application from their browser or mobile device.
The user signs in with their credentials.
A request is made to an Amazon Cognito user pool for a login authentication token, and a token is received for a successful sign-in request.
The search application calls the search API method with the token in the authorization header to API Gateway. API Gateway is protected by AWS WAF to enforce rate limiting and implement allow and deny lists.
API Gateway passes the token for validation to the Amazon Cognito user pool. Amazon Cognito validates the token and sends a response to API Gateway.
API Gateway invokes the Lambda function to process the request.
The Lambda function queries OpenSearch Serverless and returns the metadata for the search.
Based on metadata, content is returned from Amazon S3 to the user.
In the following sections, we walk you through the steps to deploy the solution, ingest data, and test the solution.
Prerequisites
Before you get started, make sure you complete the following prerequisites:
Install and configure the Amplify CLI. At the end of configuration, you should successfully set up the new user using the amplify-dev user’s AccessKeyId and SecretAccessKey in your local machine’s AWS profile.
Amplify users need additional permissions in order to deploy AWS resources. Complete the following steps to create a new inline AWS Identity and Access Management (IAM) policy and attach it to the user:
On the IAM console, choose Users in the navigation pane.
Choose the user amplify-dev.
On the Permissions tab, choose the Add permissions dropdown menu, then choose Inline policy.
In the policy editor, choose JSON.
You should see the default IAM statement in JSON format.
Copy the file contents in AddionalPermissions-Amplify, replacing the tags with your target AWS Region, account, and environment.
This environment name needs to be used when performing amplify init when bringing up the backend. The actions in the IAM statement are largely open (*) but restricted or limited by the target resources; this is done to satisfy the maximum inline policy length (2,048 characters).
Enter the updated JSON into the policy editor, then choose Next.
For Policy name, enter a name (for this post, AddionalPermissions-Amplify).
Choose Create policy.
You should now see the new inline policy attached to the user.
Deploy the solution
Complete the following steps to deploy the solution:
Clone the repository to a new folder on your desktop using the following command:
On the Amazon S3 console, open the trailer S3 bucket (created as part of the backend deployment.
Upload some movie trailers.
Make sure the file name matches the ID field in sample movie data (for example, tt1981115.mp4, tt0800369.mp4, and tt0172495.mp4). Uploading a trailer with ID tt0172495.mp4 is used as the default trailer for all movies, without having to upload one for each movie.
Test the solution
Access the application using the CloudFront distribution domain name. You can find this by opening the CloudFront console, choosing the distribution, and copying the distribution domain name into your browser.
Sign up for application access by entering your user name, password, and email address. The password should be at least eight characters in length, and should include at least one uppercase character and symbol.
After you’re logged in, you’re redirected to the Movie Finder home page.
You can search using a movie name, actor, or director, as shown in the following example. The application returns results using OpenSearch DSL.
If there’s a large number of search results, you can navigate through them using the pagination option at the bottom of the page. For more information about how the application uses pagination, see Paginating search results.
You can choose movie tiles to get more details and watch the trailer if you took the optional step of uploading a movie trailer.
You can sort the search results using the Sort by feature. The application uses the sort functionality within OpenSearch.
There are many more DSL search patterns that allow for intricate searches. See Query DSL for complete details.
Monitoring OpenSearch Serverless
Monitoring is an important part of maintaining the reliability, availability, and performance of OpenSearch Serverless and your other AWS services. AWS provides Amazon CloudWatch and AWS CloudTrail to monitor OpenSearch Serverless, report when something is wrong, and take automatic actions when appropriate. For more information, see Monitoring Amazon OpenSearch Serverless.
Clean up
To avoid unnecessary charges, clean up the solution implementation by running the following command at the project root folder you created using the git clone command during deployment:
In this post, we implemented a full-stack serverless search application using OpenSearch Serverless. This solution seamlessly integrates with various AWS services, such as Lambda for serverless computing, API Gateway for constructing RESTful APIs, IAM for robust security, Amazon Cognito for streamlined user management, and AWS WAF for safeguarding the web application against threats. By adopting a serverless architecture, this search application offers numerous advantages, including simplified deployment processes and effortless scalability, with the benefits of a managed infrastructure.
With OpenSearch Serverless, you get the same interactive millisecond response times as OpenSearch Service with the simplicity of a serverless environment. You pay only for what you use by automatically scaling resources to provide the right amount of capacity for your application without impacting performance and scale as needed. You can use OpenSearch Serverless and this reference implementation to build your own full-stack text search application.
About the Authors
Anand Komandooru is a Principal Cloud Architect at AWS. He joined AWS Professional Services organization in 2021 and helps customers build cloud-native applications on AWS cloud. He has over 20 years of experience building software and his favorite Amazon leadership principle is “Leaders are right a lot“.
Rama Krishna Ramaseshu is a Senior Application Architect at AWS. He joined AWS Professional Services in 2022 and with close to two decades of experience in application development and software architecture, he empowers customers to build well architected solutions within the AWS cloud. His favorite Amazon leadership principle is “Learn and Be Curious”.
Sachin Vighe is a Senior DevOps Architect at AWS. He joined AWS Professional Services in 2020, and specializes in designing and architecting solutions within the AWS cloud to guide customers through their DevOps and Cloud transformation journey. His favorite leadership principle is “Customer Obsession”.
Molly Wu is an Associate Cloud Developer at AWS. She joined AWS Professional Services in 2023 and specializes in assisting customers in building frontend technologies in AWS cloud. Her favorite leadership principle is “Bias for Action”.
Andrew Yankowsky is a Security Consultant at AWS. He joined AWS Professional Services in 2023, and helps customers build cloud security capabilities and follow security best practices on AWS. His favorite leadership principle is “Earn Trust”.
Amazon CodeCatalyst is a modern software development service that empowers teams to deliver software on AWS easily and quickly. Amazon CodeCatalyst provides one place where you can plan, code, and build, test, and deploy your container applications with continuous integration/continuous delivery (CI/CD) tools.
CodeCatalyst recently announced the teams feature, which simplifies management of space and project access. Enterprises can now use this feature to organize CodeCatalyst space members into teams using single sign-on (SSO) with IAM Identity Center. You can also assign SSO groups to a team, to centralize your CodeCatalyst user management. CodeCatalyst space admins can create teams made up any members of the space and assign them to unique roles per project, such as read-only or contributor.
Introduction:
In this post, we will demonstrate how enterprises can enable access to CodeCatalyst with their workforce identities configured in AWS IAM Identity Center, and also easily manage which team members have access to CodeCatalyst spaces and projects. With AWS IAM Identity Center, you can connect a self-managed directory in Active Directory (AD) or a directory in AWS Managed Microsoft AD by using AWS Directory Service. You can also connect other external identity providers (IdPs) like Okta or OneLogin to authenticate identities from the IdPs through the Security Assertion Markup Language (SAML) 2.0 standard. This enables your users to sign in to the AWS access portal with their corporate credentials.
Pre-requisites:
To get started with CodeCatalyst, you need the following prerequisites. Please review them and ensure you have completed all steps before proceeding:
1. Set up an CodeCatalyst space. To join a space, you will need to either:
Create an Amazon CodeCatalyst space that supports identity federation. If you are creating the space, you will need to specify an AWS account ID for billing and provisioning of resources. If you have not created an AWS account, follow the AWS documentation to create one
2. Create an AWS Identity and Access Management (IAM) role. Amazon CodeCatalyst will need an IAM role to have permissions to deploy the infrastructure to your AWS account. Follow the documentation for steps how to create an IAM role via the Amazon CodeCatalyst console.
3. Once the above steps are completed, you can go ahead and create projects in the space using the available blueprints or custom blueprints.
Walkthrough:
The emphasis of this post, will be on how to manage IAM identity center (SSO) groups with CodeCatalyst teams. At the end of the post, our workflow will look like the one below:
Figure 2: Architectural Diagram
For the purpose of this walkthrough, I have used an external identity provider Okta to federate with AWS IAM Identity Center to manage access to CodeCatalyst.
Figure 3: Okta Groups from Admin Console
You can also see the same Groups are synced with the IAM Identity Center instance from the figure below. Please note Groups and member management must be done only via external identity providers.
Figure 4: IAM Identity Center Groups created via SCIM synch
Now, if you go to your Okta apps and click on ‘AWS IAM Identity Center’, the AWS account ID and CodeCatalyst space that you created as part of prerequisites should be automatically configured for you via single sign-on. Developers and Administrators of the space can easily login using this integration.
Figure 5: CodeCatalyst Space via SSO
Once you are in the CodeCatalyst space, you can organize CodeCatalyst space members into teams, and configure the default roles for them. You can choose one of the three roles from the list of space roles available in CodeCatalyst that you want to assign to the team. The role will be inherited by all members of the team:
Space administrator – The Space administrator role is the most powerful role in Amazon CodeCatalyst. Only assign the Space administrator role to users who need to administer every aspect of a space, because this role has all permissions in CodeCatalyst. For details, see Space administrator role.
Power user – The Power user role is the second-most powerful role in Amazon CodeCatalyst spaces, but it has no access to projects in a space. It is designed for users who need to be able to create projects in a space and help manage the users and resources for the space. For details, see Power user role.
Limited access – It is the role automatically assigned to users when they accept an invitation to a project in a space. It provides the limited permissions they need to work within the space that contains that project. For details, see Limited access role.
In this example here, if I go into the ‘space-admin’ team, I can view the SSO group associated with it through IAM Identity Center.
Figure 7: SSO Group association with Teams
You can now use these teams from the CodeCatalyst space to help manage users and permissions for the projects in that space. There are four project roles available in CodeCatalyst:
Project administrator — The Project administrator role is the most powerful role in an Amazon CodeCatalyst project. Only assign this role to users who need to administer every aspect of a project, including editing project settings, managing project permissions, and deleting projects. For details, see Project administrator role.
Contributor — The Contributor role is intended for the majority of members in an Amazon CodeCatalyst project. Assign this role to users who need to be able to work with code, workflows, issues, and actions in a project. For details, see Contributor role.
Reviewer — The Reviewer role is intended for users who need to be able to interact with resources in a project, such as pull requests and issues, but not create and merge code, create workflows, or start or stop workflow runs in an Amazon CodeCatalyst project. For details, see Reviewer role.
Read only — The Read only role is intended for users who need to view the resources and status of resources but not interact with them or contribute directly to the project. Users with this role cannot create resources in CodeCatalyst, but they can view them and copy them, such as cloning repositories and downloading attachments to issues to a local computer. For details, see Read only role.
For the purpose of this demonstration, I have created projects from the default blueprints (I chose the modern three-tier web application blueprint) and assigned Teams to it with specific roles. You can also create a project using a default blueprint in CodeCatalyst space if you don’t already have an existing project.
Figure 8: Teams in Project Settings
You can also view the roles assigned to each of the teams in the CodeCatalyst Space settings.
Figure 9: Project roles in Space settings
Clean up your Environment:
If you have been following along with this workflow, you should delete the resources you deployed so you do not continue to incur charges. First, delete the two stacks that CDK deployed using the AWS CloudFormation console in the AWS account you associated when you launched the blueprint. If you had launched the Modern three-tier web application just like I did, these stacks will have names like mysfitsXXXXXWebStack and mysfitsXXXXXAppStack. Second, delete the project from CodeCatalyst by navigating to Project settings and choosing Delete project.
Conclusion:
In this post, you learned how to add Teams to a CodeCatalyst space and projects using SSO Groups. I used Okta for my external identity provider to connect with IAM Identity Center, but you can use your Organizations idP or any other IDP that supports SAML. You also learned how easy it is to maintain SSO group members in the CodeCatalyst space by assigning the necessary roles and restricting access when not necessary.
Today, we are pleased to announce the general availability of the Terraform AWS Cloud Control (AWS CC) Provider, enabling our customers to take advantage of AWS innovations faster. AWS has been continually expanding its services to support virtually any cloud workload; supporting over 200 fully featured services and delighting customers through its rapid pace of innovation with over 3,400 significant new features in 2023. Our customers use Infrastructure as Code (IaC) tools such as HashiCorp Terraform among others as a best-practice to provision and manage these AWS features and services as part of their cloud infrastructure at scale. With the Terraform AWS CC Provider launch, AWS customers using Terraform as their IaC tool can now benefit from faster time-to-market by building cloud infrastructure with the latest AWS innovations that are typically available on the Terraform AWS CC Provider on the day of launch. For example, AWS customer Meta’s Oculus Studios was able to quickly leverage Amazon GameLift to support their game development. “AWS and Hashicorp have been great partners in helping Oculus Studios standardize how we deploy our GameLift infrastructure using industry best practices.” said Mick Afaneh, Meta’s Oculus Studios Central Technology.
The Terraform AWS CC Provider leverages AWS Cloud Control API to automatically generate support for hundreds of AWS resource types, such as Amazon EC2 instances and Amazon S3 buckets. Since the AWS CC provider is automatically generated, new features and services on AWS can be supported as soon as they are available on AWS Cloud Control API, addressing any coverage gaps in the existing Terraform AWS standard provider. This automated process allows the AWS CC provider to deliver new resources faster because it does not have to wait for the community to author schema and resource implementations for each new service. Today, the AWS CC provider supports 950+ AWS resources and data sources, with more support being added as AWS service teams continue to adopt the Cloud Control API standard.
As a Terraform practitioner, using the AWS CC Provider would feel familiar to the existing workflow. You can employ the configuration blocks shown below, while specifying your preferred region.
During Terraform plan or apply, the AWS CC Terraform provider interacts with AWS Cloud Control API to provision the resources by calling its consistent Create, Read, Update, Delete, or List (CRUD-L) APIs.
AWS Cloud Control API
AWS service teams own, publish, and maintain resources on the AWS CloudFormation Registry using a standardized resource model. This resource model uses uniform JSON schemas and provisioning logic that codifies the expected behavior and error handling associated with CRUD-L operations. This resource model enables AWS service teams to expose their service features in an easily discoverable, intuitive, and uniform format with standardized behavior. Launched in September 2021, AWS Cloud Control API exposes these resources through a set of five consistent CRUD-L operations without any additional work from service teams. Using Cloud Control API, developers can manage the lifecycle of hundreds of AWS and third-party resources with consistent resource-oriented API instead of using distinct service-specific APIs. Furthermore, Cloud Control API is up-to-date with the latest AWS resources as soon as they are available on the CloudFormation Registry, typically on the day of launch. You can read more on launch day requirement for Cloud Control API in this blog post. This enables AWS Partners such as HashiCorp to take advantage of consistent CRUD-L API operations and integrate Terraform with Cloud Control API just once, and then automatically access new AWS resources without additional integration work.
History and Evolution of the Terraform AWS CC Provider
The general availability of Terraform AWS CC Provider project is a culmination of 4+ years of collaboration between AWS and HashiCorp. Our teams partnered across the Product, Engineering, Partner, and Customer Support functions in influencing, shaping, and defining the customer experience leading up to the the technical preview announcement of the AWS CC provider in September 2021. At technical preview, the provider supported more than 300 resources. Since then, we have added an additional 600+ resources to the provider, bringing the total to 950+ supported resources at general availability.
Beyond just increasing resource coverage, we gathered additional signals from customer feedback during the technical preview and rolled out several improvements since September 2021. Customers care deeply about the user experience on the providers available on the Terraform registry. Customers sought practical examples in the form of sample HCL configurations for each resource that they could use to immediately test in order to confidently start using the provider. This prompted us to enrich the AWS CC provider with hundreds of practical examples for popular AWS CC provider resources in the Terraform registry. This was made possible by contributions of hundreds of Amazonians who became early adopters of the AWS CC provider. We also published a how-to guide for anyone interested in contributing to AWS CC provider examples. Furthermore, customers also wanted to minimize context switching by moving between Terraform and AWS service documentation on what each attribute of a resource signified and the type of values it needed as part of configuration. This empowered us to prioritize augmenting the provider with rich resource attribute description with information taken from AWS documentation. The documentation provides detailed information of how to use the attributes, enumerations of the accepted attribute values and other relevant information for dozens of popularly used AWS resources.
We also worked with HashiCorp on various bug fixes and feature enhancements for the AWS CC provider, as well as the upstream Cloud Control API dependencies. We improved handling for resources with complex nested attribute schemas, implemented various bug fixes to resolve unintended resource replacement, and refined provider behavior under various conditions to support the idempotency expected by Terraform practitioners. While this are not an exhaustive list of improvements, we continue to listen to customer feedback and iterate on improving the experience. We encourage you to try out the provider and share feedback on the AWS CC provider’s GitHub page.
Using the AWS CC Provider
Let’s take an example of a recently introduced service, Amazon Q Business, a fully managed, generative AI-powered assistant that you can configure to answer questions, provide summaries, generate content, and complete tasks based on your enterprise data. Amazon Q Business resources were available in AWS CC provider shortly after the April 30th 2024 launch announcement. In the following example, we’ll create a demo Amazon Q Business application and deploy the web experience.
As you see in this example, you can use both the AWS and AWS CC providers in the same configuration file. This allows you to easily incorporate new resources available in the AWS CC provider into your existing configuration with minimal changes. The AWS CC provider also accepts the same authentication method and provider-level features available in the AWS provider. This means you don’t have to add additional configuration in your CI/CD pipeline to start using the AWS CC provider. In addition, you can also add custom agent information inside the provider block as described in this documentation.
Things to know
The AWS CC provider is unique due to how it was developed and its dependencies with Cloud Control API and AWS resource model in the CloudFormation registry. As such, there are things that you should know before you start using the AWS CC provider.
The AWS CC provider is generated from the latest CloudFormation schemas, and will release weekly containing all new AWS services and enhancements added to Cloud Control API.
Certain resources available in the CloudFormation schema are not compatible with the AWS CC provider due to nuances in the schema implementation. You can find them on the GitHub issue list here. We are actively working to add these resources to the AWS CC provider.
The AWS CC provider requires Terraform CLI version 1.0.7 or higher.
Every AWS CC provider resource includes a top-level attribute `id` that acts as the resource identifier. If the CloudFormation resource schema also has a similarly named top-level attribute `id`, then that property is mapped to a new attribute named `<type>_id`. For example `web_experience_id` for `awscc_qbusiness_web_experience` resource.
If a resource attribute is not defined in the Terraform configuration, the AWS CC provider will honor the default values specified in the CloudFormation resource schema. If the resource schema does not include a default value, AWS CC provider will use attribute value stored in the Terraform state (taken from Cloud Control API GetResponse after resource was created).
In correlation to the default value behavior as stated above, when an attribute value is removed from the Terraform configuration (e.g. by commenting the attribute), the AWS CC provider will use the previous attribute value stored in the Terraform state. As such, no drift will be detected on the resource configuration when you run Terraform plan / apply.
The AWS CC provider data sources are either plural or singular with filters based on `id` attribute. Currently there is no native support for metadata sources such as `aws_region` or `aws_caller_identity`. You can continue to leverage the AWS provider data sources to complement your Terraform configuration.
If you want to dive deeper into AWS CC provider resource behavior, we encourage you to check the documentation here.
Conclusion
The AWS CC provider is now generally available and will be the fastest way for customers to access newly launched AWS features and services using Terraform. We will continue to add support for more resources, additional examples and enriching the schema descriptions. You can start using the AWS CC provider alongside your existing AWS standard provider. To learn more about the AWS CC provider, please check the HashiCorp announcement blog post. You can also follow the workshop on how to get started with AWS CC provider. If you are interested in contributing with practical examples for AWS CC provider resources, check out the how-to guide. For more questions or if you run into any issues with the new provider, don’t hesitate to submit your issue in the AWS CC provider GitHub repository.
In this post, we’ll show how you can use AWS Private Certificate Authority (AWS Private CA) to issue a wide range of X.509 certificates that are tailored for specific use cases. These use-case bound certificates have their intended purpose defined within the certificate components, such as the Key Usage and Extended Key usage extensions. We will guide you on how you can define your usage by applying your required Key Usage and Extended Key usage values with the IssueCertificate API operation.
Background
With the AWS Private CA service, you can build your own public key infrastructure (PKI) in the AWS Cloud and issue certificates to use within your organization. Certificates issued by AWS Private CA support both the Key Usage and Extended Key Usage extensions. By using these extensions with specific values, you can bind the usage of a given certificate to a particular use case during creation. Binding certificates to their intended use case, such as SSL/TLS server authentication or code signing, provides distinct security benefits such as accountability and least privilege.
When you define certificate usage with specific Key Usage and Extended Key Usage values, this helps your organization understand what purpose a given certificate serves and the use case for which it is bound. During audits, organizations can inspect their certificate’s Key Usage and Extended Key Usage values to determine the certificate’s purpose and scope. This not only provides accountability regarding a certificate’s usage, but also a level of transparency for auditors and stakeholders. Furthermore, by using these extensions with specific values, you will follow the principle of least privilege. You can grant least privilege by defining only the required Key Usage and Extended Key Usage values for your use case. For example, if a given certificate is going to be used only for email protection (S/MIME), you can assign only that extended key usage value to the certificate.
Certificate templates and use cases
In AWS Private CA, the Key Usage and Extended Key Usage extensions and values are specified by using a configuration template, which is passed with the IssueCertificate API operation. The base template provided by AWS handles the most common certificate use cases, such as SSL/TLS server authentication or code signing. However, there are additional use cases for certificates that are not defined in base templates. To issue certificates for these use cases, you can pass blank certificate templates in your IssueCertificate requests, along with your required Key Usage and Extended Key usage values.
Such use cases include, but are not limited to the following:
Certificates for SSL/TLS
Issue certificates with an Extended Key Usage value of Server Authentication, Client Authentication, or both.
Certificates for email protection (S/MIME)
Issue certificates with an Extended Key Usage value of E-mail Protection
Certificates for smart card authentication (Microsoft Smart Card Login)
Issue certificates with an Extended Key Usage value of Smart Card Logon
Certificates for document signing
Issue certificates with an Extended Key Usage value of Document Signing
Certificates for code signing
Issue certificates with an Extended Key Usage value of Code Signing
If your certificates require less-common extended key usage values not defined in the AWS documentation, you can also pass object identifiers (OIDs) to define values in Extended Key Usage. OIDs are dotted-string identifiers that are mapped to objects and attributes. OIDs can be defined and passed with custom extensions using API passthrough. You can also define OIDs in a CSR (certificate signing request) with a CSR passthrough template. Such uses include:
Certificates that require IPSec or virtual private network (VPN) related extensions
Issue certificates with Extended Key Usage values:
Pass the ISO/IEC 18013-5 OID reserved for mDL DS: 1.0.18013.5.1.2 by using custom extensions.
It’s important to note that blank certificate templates aren’t limited to just end-entity certificates. For example, the BlankSubordinateCACertificate_PathLen0_APICSRPassthrough template sets the Basic constraints parameter to CA:TRUE, allowing you to issue a subordinate CA certificate with your own Key Usage and Extended Key Usage values.
Using blank certificate templates
When you browse through the AWS Private CA certificate templates, you may see that base templates don’t allow you to define your own Key Usage or Extended Key Usage extensions and values. They are preset to the extensions and values used for the most common certificate types in order to simplify issuing those types of certificates. For example, when using EndEntityCertificate/V1, you will always get a Key Usage value of Critical, digital signature, key encipherment and an Extended Key Usage value of TLS web server authentication, TLS web client authentication. The following table shows all of the values for this base template.
EndEntityCertificate/V1
X509v3 parameter
Value
Subject alternative name
[Passthrough from certificate signing request (CSR)]
Subject
[Passthrough from CSR]
Basic constraints
CA:FALSE
Authority key identifier
[Subject key identifier from CA certificate]
Subject key identifier
[Derived from CSR]
Key usage
Critical, digital signature, key encipherment
Extended key usage
TLS web server authentication, TLS web client authentication
CRL distribution points
[Passthrough from CA configuration]
When you look at blank certificate templates, you will see that there is more flexibility. For one example of a blank certificate template, BlankEndEntityCertificate_APICSRPassthrough/V1, you can see that there are fewer predefined values compared to EndEntityCertificate/V1. You can pass your own values for Extended Key Usage and Key Usage.
BlankEndEntityCertificate_APICSRPassthrough/V1
X509v3 parameter
Value
Subject alternative name
[Passthrough from API or CSR]
Subject
[Passthrough from API or CSR]
Basic constraints
CA:FALSE
Authority key identifier
[Subject key identifier from CA certificate]
Subject key identifier
[Derived from CSR]
CRL distribution points
Note: CRL distribution points are included in the template only if the CA is configured with CRL generation enabled.
API Passthrough – Extensions and their values defined in the IssueCertificate parameter APIPassthrough are copied over to the issued certificate.
CSR Passthrough – Extensions and their values defined in the CSR are copied over to the issued certificate.
To accommodate the different ways of passing these values, there are three varieties of blank certificate templates. If you would like to pass extensions defined only in your CSR file to the issued certificate, you can use the BlankEndEntityCertificate_CSRPassthrough/V1 template. Similarly, if you would like to pass extensions defined only in the APIPassthrough parameter, you can use the BlankEndEntityCertificate_APIPassthrough/V1 template. Finally, if you would like to use a combination of extensions defined in both the CSR and APIPassthrough, you can use the BlankEndEntityCertificate_APICSRPassthrough/V1 template. It’s important to remember these points when choosing your template:
The template definition will always have the higher priority over the values specified in the CSR, regardless of what template variety you use. For example, if the template contains a Key Usage value of digital signature and your CSR file contains key encipherment, the certificate will choose the template definition digital signature.
API passthrough values are only respected when you use an API passthrough or APICSR passthrough template. CSR passthrough is only respected when you use a CSR passthrough or APICSR passthrough template. When these sources of information are in conflict (the CSR contains the same extension or value as what’s passed in API passthrough), a general rule usually applies: For each extension value, the template definition has highest priority, followed by API passthrough values, followed by CSR passthrough extensions. Read more about the template order of operations in the AWS documentation.
How to issue use-case bound certificates in the AWS CLI
After verifying the status, make note of your private CA Amazon Resource Name (ARN).
To issue use-case bound certificates, you must use the Private CA API operation IssueCertificate.
In the AWS CLI, you can call this API by using the command issue-certificate. There are several parameters you must pass with this command:
(--certificate-authority-arn) – The ARN of your private CA.
(--csr) – The CSR in PEM format. It must be passed as a blob , like fileb://.
(--validity) – Sets the “Not After” date (expiration date) for the certificate.
(--signing-algorithm) – The signing algorithm to be used to sign the certificate. The value you choose must match the algorithm family of the private CA’s algorithm (RSA or ECDSA). For example, if the private CA uses RSA_2048, the signing algorithm must be an RSA variant, like SHA256WITHRSA.
You can check your private CA’s algorithm family by referring to its key algorithm. The command aws acm-pca describe-certificate-authority will show the corresponding KeyAlgorithm value.
(--template-arn) – This is where the blank certificate template is defined. The template should be an AWS Private CA template ARN. The full list of AWS Private CA template ARNs are shown in the AWS documentation.
We’ll now demonstrate how to issue use-case bound end-entity certificates by using blank end-entity certificate templates. We will issue two different certificates. One will be bound for email protection, and one will be bound for smart card authentication. Email protection and smart card authentication certificates have specific Extended Key Usage values which are not defined by any base template. We’ll use CSR passthrough to issue the smart card authentication certificate and use API passthrough to issue the email protection certificate.
The certificate templates that we will use are:
For CSR passthrough: BlankEndEntityCertificate_CSRPassthrough/V1
For API Passthrough: BlankEndEntityCertificate_APIPassthrough/V1
Important notes about this demo:
These commands are for demo purposes only. Depending on your specific use case, email protection certificates and smart card authentication certificates may require different extensions than what’s shown in this demo.
You will be generating RSA 2048 private keys. Private keys need to be protected and stored properly and securely. For example, encrypting private keys or storing private keys in a hardware security module (HSM) are some methods of protection that you can use.
We will be using the OpenSSL command line tool, which is installed by default on many operating systems such as Amazon Linux 2023. If you don’t have this tool installed, you can obtain it by using the software distribution facilities of your organization or your operating system, as appropriate.
Use API passthrough
We will now demonstrate how to issue a certificate that is bound for email protection. We’ll specify Key Usage and Extended Key Usage values, and also a subject alternative name through API passthrough. The goal is to have these extensions and values in the email protection certificate.
Extensions:
	X509v3 Key Usage: critical
	Digital Signature, Key Encipherment
	X509v3 Extended Key Usage:
	E-mail Protection
	X509v3 Subject Alternative Name:
	email:[email protected]
To issue a certificate bound for email protection
Use the following command to create your keypair and CSR with OpenSSL. Define your distinguished name in the OpenSSL prompt.
Use the following command to issue an end-entity certificate specifying the EMAIL_PROTECTION extended key usage value, the Digital Signature and Key Encipherment Key Usage values, and the subject alternative name [email protected]. We will use the Rfc822Name subject alternative name type, because the value is an email address.
Make sure to replace the data in arn:aws:acm-pca:<region>:<accountID>:certificate-authority/11111111-1111-1111-1111-111111111111 with your private CA ARN, and adjust the signing algorithm according to your private CA’s algorithm. Assuming my PCA is type RSA, I am using SHA256WITHRSA.
Proceed to the Retrieve the Certificate section of this post to retrieve the certificate and certificate chain PEM from the CertificateArn.
Use CSR passthrough
We’ll now demonstrate how to issue a certificate that is bound for smart card authentication. We will specify Key Usage, Extended Key Usage, and subject alternative name extensions and values through CSR passthrough. The goal is to have these values in the smart card authentication certificate.
Extensions:
	X509v3 Key Usage: critical
	Digital Signature
	X509v3 Extended Key Usage:
	TLS Web Client Authentication, Microsoft Smartcard Login
	X509v3 Subject Alternative Name:
	othername: UPN::[email protected]
We’ll generate our CSR by requesting these specific extensions and values with OpenSSL. When we call IssueCertificate, the CSR passthrough template will acknowledge the requested extensions and copy them over to the issued certificate.
To issue a certificate bound for smart card authentication
Use the following command to create the private key.
Create a file called openssl_csr.conf to define the distinguished name and the requested CSR extensions.
Following is an example of OpenSSL configuration file content. You can copy this configuration to the openssl_csr.conf file and adjust the values to your requirements. You can find further reference on the configuration in the OpenSSL documentation.
[ req ]
default_bits = 2048
prompt = no
default_md = sha256
req_extensions = my_req_ext
distinguished_name = dn

#Specify the Distinguished Name
[ dn ]
countryName                     = US
stateOrProvinceName             = VA
localityName                    = Test City
organizationName                = Test Organization Inc
organizationalUnitName          = Test Organization Unit
commonName                      = john_doe


#Specify the Extensions
[ my_req_ext ]
keyUsage = critical, digitalSignature
extendedKeyUsage = clientAuth, msSmartcardLogin

#UPN OtherName OID: "1.3.6.1.4.1.311.20.2.3". Value is ASN1-encoded UTF8 string
subjectAltName = otherName:msUPN;UTF8:[email protected]
In this example, you can specify your Key Usage and Extended Key Usage values in the [ my_req_ext ] section of the configuration. In the extendedKeyUsage line, you may also define extended key usage OIDs, like 1.3.6.1.4.1.311.20.2.2. Possible values are defined in the OpenSSL documentation.
(Optional) You can use the following command to decode the CSR to make sure it contains the information you require.
openssl req -in csr-demo-2.csr -noout -text
The output should show the requested extensions and their values, as follows.
	X509v3 Key Usage: critical
	Digital Signature
	X509v3 Extended Key Usage:
	TLS Web Client Authentication, Microsoft Smartcard Login
	X509v3 Subject Alternative Name:
	othername: UPN:: <your_user_here>
Issue the certificate by using the issue-certificate command. We will use a CSR passthrough template so that the requested extensions and values in the CSR file are copied over to the issued certificate.
Make sure to replace the data in arn:aws:acm-pca:us-east-1:<accountID>:certificate-authority/11111111-1111-1111-1111-111111111111 with your private CA ARN and adjust the signing algorithm and validity to for your use case. Assuming my PCA is type RSA, I am using SHA256WITHRSA.
After using issue-certificate with API passthrough or CSR passthrough, you can retrieve the certificate material in PEM format. Use the get-certificate command and specify the ARN of the private CA that issued the certificate, as well as the ARN of the certificate that was issued:
aws acm-pca get-certificate --certificate-arn arn:aws:acm-pca:us-east-1:<accountID>:certificate-authority/11111111-1111-1111-1111-111111111111/certificate/123465789123456789 --certificate-authority-arn arn:aws:acm-pca:us-east-1:<accountID>:certificate-authority/11111111-1111-1111-1111-111111111111 --output text
You can use the --query command with the AWS CLI to get the certificate and certificate chain in separate files.
After you retrieve the certificate, you can decode it with the openssl x509 command. This will allow you to view the details of the certificate, including the extensions and values that you defined.
openssl x509 -in certfile.pem -noout -text
Conclusion
In AWS Private CA, you can implement the security benefits of accountability and least privilege by defining the usage of your certificates. The Key Usage and Extended Key Usage values define the usage of your certificates. Many certificate use cases require a combination of Key Usage and Extended Key Usage values, which cannot be defined with base certificate templates. Some examples include document signing, smart card authentication, and mobile driving license (mDL) certificates. To issue certificates for these specific use cases, you can use blank certificate templates with the IssueCertificate API call. In addition to the blank certificate template, you must also define the specific combination of Key Usage and Extended Key Usage values through CSR passthrough, API passthrough, or both.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
A data perimeter on Amazon Web Services (AWS) is a set of preventive controls you can use to help establish a boundary around your data in AWS Organizations. This boundary helps ensure that your data can be accessed only by trusted identities from within networks you expect and that the data cannot be transferred outside of your organization to untrusted resources. Review the previous posts in the Establishing a data perimeter on AWS series for information about the security objectives and foundational elements needed to define and enforce each perimeter type.
In this blog post, we discuss how to use AWS logging and analytics capabilities to help accelerate the implementation and effectively operate data perimeter controls at scale.
You start your data perimeter journey by identifying access patterns that you want to prevent and defining what trusted identities, trusted resources, and expected networks mean to your organization. After you define your trust boundaries based on your business and security requirements, you can use policy examples provided in the data perimeter GitHub repository to design the authorization controls for enforcing these boundaries. Before you enforce the controls in your organization, we recommend that you assess the potential impacts on your existing workloads. Performing the assessment helps you to identify unknown data access patterns missed during the initial design phase, investigate, and refine your controls to help ensure business continuity as you deploy them.
Finally, you should continuously monitor your controls to verify that they operate as expected and consistently align with your requirements as your business grows and relationships with your trusted partners change.
Figure 1 illustrates common phases of a data perimeter journey.
Figure 1: Data perimeter implementation journey
The usual phases of the data perimeter journey are:
Examine your security objectives
Set your boundaries
Design data perimeter controls
Anticipate potential impacts
Implement data perimeter controls
Monitor data perimeter controls
Continuous improvement
In this post, we focus on phase 4: Anticipate potential impacts. We demonstrate how to analyze activity observed in your AWS environment to evaluate impact and refine your data perimeter controls. We also demonstrate how you can automate the analysis by using the data perimeter helper open source tool.
You can use the same techniques to support phase 6: Monitor data perimeter controls, where you will continuously monitor data access patterns in your organization and potentially troubleshoot permissions issues caused by overly restrictive or overly permissive policies as new data access paths are introduced.
Setting prerequisites for impact analysis
In this section, we describe AWS logging and analytics capabilities that you can use to analyze impact of data perimeter controls on your environment. We also provide instructions for configuring them.
While you might have some capabilities covered by other AWS tools (for example, AWS Security Lake) or external tools, the proposed approach remains applicable. For instance, if your logs are stored in an external security data lake or your configuration state recording is performed by an external cloud security posture management (CSPM) tool, you can extract and adapt the logic from this post to suit your context. The flexibility of this approach allows you to use the existing tools and processes in your environment while benefiting from the insights provided.
Pricing
Some of the required capabilities can generate additional costs in your environment.
Amazon Athena charges based on the number of terabytes of data scanned in Amazon S3. To help control costs, use the proposed optimized tables with partitioning and reduce the time frame of your queries. For more details, see Athena pricing.
Create a CloudTrail trail to record access activity
The primary capability that you will use is a CloudTrail trail. CloudTrail records AWS API calls and events from your AWS accounts that contain the following information relevant to data perimeter objectives:
API calls performed by your identities or on your resources (record fields: eventSource, eventName)
Identity that performed API calls (record field: userIdentity)
Network origin of API calls (record fields: sourceIPAddress, vpcEndpointId)
Resources API calls are performed on (record fields: resources, requestParameters)
Data perimeter controls are meant to be applied across a broad set of accounts and resources, therefore, we recommend using a CloudTrail organization trail that collects logs across the AWS accounts in your organization. If you don’t have an organization trail configured, follow these steps or use one of the data perimeter helper templates for deploying prerequisites. If you use AWS services that support CloudTrail data events and want to analyze the associated API calls, enable the relevant data events.
Though CloudTrail provides you information about parameters of an API request, it doesn’t reflect values of AWS Identity and Access Management (IAM) condition keys present in the request. Thus, you still need to analyze the logs to help refine your data perimeter controls.
Create an Athena table to analyze CloudTrail logs
To ease and accelerate logs analysis, use Athena to query and extract relevant data from the log files stored by CloudTrail in an S3 bucket.
Next, navigate to the Query editor and create a SQL table by entering the following DDL statement into the Athena console query editor. Make sure to replace s3://<BUCKET_NAME_WITH_PREFIX>/AWSLogs/<ORGANIZATION_ID>/ to point to the S3 bucket location that contains your CloudTrail log data and <REGIONS> with the list of AWS regions where you want to analyze API calls. For example, to analyze API calls made in the AWS Regions Paris (eu-west-3) and North Virginia (us-east-1), use eu-west-3,us-east-1. We recommend that you include us-east-1 to retrieve API calls performed on global resources such as IAM roles.
Finally, run the Athena query and confirm that the cloudtrail_logs table is created and appears under the list of Tables.
Create an AWS Config aggregator to enrich query results
To further reduce manual steps for retrieval of relevant data about your environment, use the AWS Config aggregator and advanced queries to enrich CloudTrail logs with the configuration state of your resources.
Create an IAM Access Analyzer external access analyzer
To identify resources in your organization that are shared with an external entity, use the IAM Access Analyzer external access analyzer with your organization as the zone of trust.
You can use an existing external access analyzer or create a new one.
Install the data perimeter helper tool
Finally, you will use the data perimeter helper, an open-source tool with a set of purpose-built data perimeter queries, to automate the logs analysis process.
Analyze account activity and refine your data perimeter controls
In this section, we provide step-by-step instructions for using the AWS services and tools you configured to effectively implement common data perimeter controls. We first demonstrate how to use the configured CloudTrail trail, Athena table, and AWS Config aggregator directly. We then show you how to accelerate the analysis with the data perimeter helper.
Example 1: Review API calls to untrusted S3 buckets and refine your resource perimeter policy
One of the security objectives targeted by companies is ensuring that their identities can only put or get data to and from S3 buckets belonging to their organization to manage the risk of unintended data disclosure or access to unapproved data. You can help achieve this security objective by implementing a resource perimeter on your identities using a service control policy (SCP). Start crafting your policy by referring to the resource_perimeter_policy template provided in the data perimeter policy examples repository:
Replace the value of the aws:ResourceOrgID condition key with your organization identifier. See the GitHub repository README file for information on other elements of the policy.
As a security engineer, you can anticipate potential impacts by reviewing account activity and CloudTrail logs. You can perform this analysis manually or use the data perimeter helper tool to streamline the process.
First, let’s explore the manual approach to understand each step in detail.
Perform impact analysis without tooling
To assess the effects of the preceding policy before deployment, review your CloudTrail logs to understand on which S3 buckets API calls are performed. The targeted Amazon S3 API calls are recorded as CloudTrail data events, so make sure you enable the S3 data event for this example. CloudTrail logs provide request parameters from which you can extract the bucket names.
Below is an example Athena query to list the targeted S3 API calls made by principals in the selected account within the last 7 days. The 7-day timeframe is set to verify that the query runs quickly, but you can adjust the timeframe later to suit your specific requirements and obtain more realistic results. Replace <ACCOUNT_ID> with the AWS account ID you want to analyze the activity of.
SELECT
  useridentity.sessioncontext.sessionissuer.arn AS principal_arn,
  useridentity.type AS principal_type,
  eventname,
  JSON_EXTRACT_SCALAR(requestparameters, '$.bucketName') AS bucketname,
  resources,
  COUNT(*) AS nb_reqs
FROM "cloudtrail_logs"
WHERE
  p_account = '<ACCOUNT_ID>'
  AND p_date BETWEEN DATE_FORMAT(CURRENT_DATE - INTERVAL '7' day, '%Y/%m/%d') AND DATE_FORMAT(CURRENT_DATE, '%Y/%m/%d')
  AND eventsource = 's3.amazonaws.com'
  -- Get only requests performed by principals in the selected account
  AND useridentity.accountid = '<ACCOUNT_ID>'
  -- Keep only the targeted API calls
  AND eventname IN ('GetObject', 'PutObject', 'PutObjectAcl')
  -- Remove API calls made by AWS service principals - `useridentity.principalid` field in CloudTrail log equals `AWSService`.
  AND useridentity.principalid != 'AWSService'
  -- Remove API calls made by service-linked roles in the selected account
    AND COALESCE(NOT regexp_like(useridentity.sessioncontext.sessionissuer.arn, '(:role/aws-service-role/)'), True)
  -- Remove calls with errors
  AND errorcode IS NULL
GROUP BY
  useridentity.sessioncontext.sessionissuer.arn,
  useridentity.type,
  eventname,
  JSON_EXTRACT_SCALAR(requestparameters, '$.bucketName'),
  resources
As shown in Figure 2, this query provides you with a list of the S3 bucket names that are being accessed by principals in the selected account, while removing calls made by service-linked roles (SLRs) because they aren’t governed by SCPs. In this example, the IAM roles AppMigrator and PartnerSync performed API calls on S3 buckets named app-logs-111111111111, raw-data-111111111111, expected-partner-999999999999, and app-migration-888888888888.
Figure 2: Sample of the Athena query results
The CloudTrail record field resources provides information on the list of resources accessed in an event. The field is optional and can notably contain the resource Amazon Resource Names (ARNs) and the account ID of the resource owner. You can use this record field to detect resources owned by accounts not in your organization. However, because this record field is optional, to scale your approach you can also use the AWS Config aggregator data to list resources currently deployed in your organization.
To know if the S3 buckets belong to your organization or not, you can run the following AWS Config advanced query. This query lists the S3 buckets inventoried in your AWS Config organization aggregator.
SELECT
  accountId,
  awsRegion,
  resourceId
WHERE
  resourceType = 'AWS::S3::Bucket'
As shown in Figure 3, buckets expected-partner-999999999999 and app-migration-888888888888 aren’t inventoried and therefore don’t belong to this organization.
Figure 3: Sample of the AWS Config advanced query results
By combining the results of the Athena query and the AWS Config advanced query, you can now pinpoint S3 API calls made by principals in the selected account on S3 buckets that are not part of your AWS organization.
If you do nothing, your starting resource perimeter policy would block access to these buckets. Therefore, you should investigate with your development teams why your principals performed those API calls and refine your policy if there is a legitimate reason, such as integration with a trusted third party. If you determine, for example, that your principals have a legitimate reason to access the bucket expected-partner-999999999999, you can discover the account ID (<third-party-account-a>) that owns the bucket by reviewing the record field resources in your CloudTrail logs or investigating with your developers and edit the policy as follows:
Now your resource perimeter policy helps ensure that access to resources that belong to your trusted third-party partner aren’t blocked by default.
Automate impact analysis with the data perimeter helper
Data perimeter helper provides queries that perform and combine the results of Athena and AWS Config aggregator queries on your behalf to accelerate policy impact analysis.
For this example, we use the s3_scp_resource_perimeter query to analyze S3 API calls made by principals in a selected account on S3 buckets not owned by your organization or inventoried in your AWS Config aggregator.
You can first add the bucket names of your trusted third-party partners that are already known in the data perimeter helper configuration file (resource_perimeter_trusted_bucket parameter). You then run the data perimeter helper query using the following command. Replace <ACCOUNT_ID> with the AWS account ID you want to analyze the activity of.
S3 API calls made on buckets that your organization owns
S3 API calls made on buckets listed as trusted in the data perimeter helper configuration file (resource_perimeter_trusted_bucket parameter)
API calls made by service principals and SLRs because SCPs don’t apply to them
API calls with errors
Gets the list of S3 buckets in your organization using an AWS Config advanced query.
Removes from the Athena query’s results API calls performed on S3 buckets inventoried in your AWS Config aggregator. This is done as a second clean-up layer in case the optional CloudTrail record field resources isn’t populated.
Data perimeter helper exports the results in the selected format (HTML, Excel, or JSON) so that you can investigate API calls that don’t align with your initial resource perimeter policy. Figure 4 shows a sample of results in HTML:
Figure 4: Sample of the s3_scp_resource_perimeter query results
The preceding data perimeter helper query results indicate that the IAM role PartnerSync performed API calls on S3 buckets that aren’t part of the organization, giving you a head start in your investigation efforts. Following the investigation, you can document a trusted partner bucket in the data perimeter helper configuration file to filter out the associated API calls from subsequent queries:
With a single command line, you have identified for your selected account the S3 API calls crossing your resource perimeter boundaries. You can now refine and implement your controls while lowering the risk of potential impacts. If you want to scale your approach to other accounts, you just need to run the same query against them.
Example 2: Review granted access and API calls by untrusted identities on your S3 buckets and refine your identity perimeter policy
Another security objective pursued by companies is ensuring that their S3 buckets can be accessed only by principals belonging to their organization to manage the risk of unintended access to company data. You can help achieve this security objective by implementing an identity perimeter on your buckets. You can start by crafting your identity perimeter policy using policy samples provided in the data perimeter policy examples repository.
Replace values of the aws:PrincipalOrgID and aws:PrincipalAccount condition keys based on what trusted identities mean for your organization and on your knowledge of the intended access patterns you need to support. See the GitHub repository README file for information on elements of the policy.
To assess the effects of the preceding policy before deployment, review your IAM Access Analyzer external access findings to discover the external entities that are allowed in your S3 bucket policies. Then to accelerate your analysis, review your CloudTrail logs to learn who is performing API calls on your S3 buckets. This can help you accelerate the removal of granted but unused external accesses.
Data perimeter helper provides queries that streamline these processes for you:
Run these queries by using the following command, replacing <ACCOUNT_ID> with the AWS account ID of the buckets you want to analyze the access activity of:
The query s3_external_access_org_boundary performs this action:
Extracts IAM Access Analyzer external access findings from either:
IAM Access Analyzer if the variable external_access_findings in the data perimeter variable file is set to IAM_ACCESS_ANALYZER
AWS Security Hub if the same variable is set to SECURITY_HUB. Security Hub provides cross-Region aggregation, enabling you to retrieve external access findings across your organization
The query s3_external_access_org_boundary performs this action:
Runs an Athena query to list S3 API calls made on S3 buckets in the selected account, filtering out:
API calls made by principals in the same organization
API calls made by principals belonging to trusted accounts listed in the data perimeter configuration file (identity_perimeter_trusted_account parameter)
API calls made by trusted identities listed in the data perimeter configuration file (identity_perimeter_trusted_principal parameter)
Figure 5 shows a sample of results for this query in HTML:
Figure 5: Sample of the s3_bucket_policy_identity_perimeter_org_boundary and s3_external_access_org_boundary queries results
The result shows that only the bucket my-bucket-open-to-partner grants access (PutObject) to principals not in your organization. Plus, in the configured time frame, your CloudTrail trail hasn’t recorded S3 API calls made by principals not in your organization on buckets that the account 111111111111 owns.
This means that your proposed identity perimeter policy accounts for the access patterns observed in your environment. After reviewing with your developers, if the granted action on the bucket my-bucket-open-to-partner is not needed, you could deploy it on the analyzed account with a reduced risk of impacting business applications.
Example 3: Investigate resource configurations to support network perimeter controls implementation
Before implementing the preceding policy or to continuously review the configuration of your Lambda functions, you can use your AWS Config aggregator to understand whether there are functions in your environment that aren’t attached to a VPC.
Data perimeter helper provides the referential_lambda_function query that helps you automate the analysis. Run the query by using the following command:
Figure 6 shows a sample of results for this query in HTML:
Figure 6: Sample of the referential_lambda_function query results
By reviewing the inVpc column, you can quickly identify functions that aren’t currently associated with a VPC and investigate with your development teams before enforcing your network perimeter controls.
Example 4: Investigate access denied errors to help troubleshoot your controls
While you refine your data perimeter controls or after deploying them, you might encounter API calls that fail with an access denied error message. You can use CloudTrail logs to review those API calls and use the record to investigate the root-cause.
Data perimeter helper provides the common_only_denied query, which lists the API calls with access denied errors in the configured time frame. Run the query by using the following command, replacing <ACCOUNT_ID> with your account ID:
Figure 7 shows a sample of results for this query in HTML:
Figure 7: Sample of the common_only_denied query results
Let’s say you want to review S3 API calls with access denied error messages for one of your developers who uses a role called DevOps. You can update, in the HTML report, the input fields below the principal_arn and eventsource columns to match your lookup.
Then by reviewing the columns principal_arn, eventname, isAssumableBy, and nb_reqs, you learn that the role DevOps is assumable through a SAML provider and performed two GetObject API calls that failed with an access denied error message. By reviewing the sourceipaddress field you discover that the request has been performed from an IP address outside of your network perimeter boundary, you can then advise your developer to perform the API calls again from an expected network.
If you followed the configuration steps in this blog only to test the solution, you can clean up your account to avoid recurring charges.
If you used the data perimeter helper deployment templates, use the respective infrastructure as code commands to delete the provisioned resources (for example, for Terraform, terraform destroy).
To delete configured resources manually, follow these steps:
Navigate to the Amazon S3 console and delete the S3 bucket you created to store CloudTrail logs from all accounts.
If you created an Athena table:
Navigate to the Athena console and select Query editor in the left navigation panel.
Run the following SQL query by replacing <TABLE_NAME> with the name of the created table:
DROP TABLE <TABLE_NAME>
If you created an AWS Config aggregator:
Navigate to the AWS Config console and select Aggregators in the left navigation panel.
Select the created aggregator and select Delete from the Actions drop-down list.
If you installed data perimeter helper:
Follow the uninstallation steps in the data perimeter helper README file.
Conclusion
In this blog post, we reviewed how you can analyze access activity in your organization by using the CloudTrail logs to evaluate impact of your data perimeter controls and perform troubleshooting. We discussed how the log events data can be enriched using resource configuration information from AWS Config to streamline your analysis. Finally, we introduced the open source tool, data perimeter helper, that provides a set of data perimeter tailored queries to speed up your review process and a framework to create new queries.
For additional learning opportunities, see the Data perimeters on AWS page, which provides additional material such as a data perimeter workshop, blog posts, whitepapers, and webinar sessions.
Many organizations use external identity providers (IdPs) such as Okta or Microsoft Azure Active Directory to manage their enterprise user identities. These users interact with and run analytical queries across AWS analytics services. To enable them to use the AWS services, their identities from the external IdP are mapped to AWS Identity and Access Management (IAM) roles within AWS, and access policies are applied to these IAM roles by data administrators.
Given the diverse range of services involved, different IAM roles may be required for accessing the data. Consequently, administrators need to manage permissions across multiple roles, a task that can become cumbersome at scale.
To address this challenge, you need a unified solution to simplify data access management using your corporate user identities instead of relying solely on IAM roles. AWS IAM Identity Center offers a solution through its trusted identity propagation feature, which is built upon the OAuth 2.0 authorization framework.
With trusted identity propagation, data access management is anchored to a user’s identity, which can be synchronized to IAM Identity Center from external IdPs using the System for Cross-domain Identity Management (SCIM) protocol. Integrated applications exchange OAuth tokens, and these tokens are propagated across services. This approach empowers administrators to grant access directly based on existing user and group memberships federated from external IdPs, rather than relying on IAM users or roles.
In this post, we showcase the seamless integration of AWS analytics services with trusted identity propagation by presenting an end-to-end architecture for data access flows.
Solution overview
Let’s consider a fictional company, OkTank. OkTank has multiple user personas that use a variety of AWS Analytics services. The user identities are managed externally in an external IdP: Okta. User1 is a Data Analyst and uses the Amazon Athena query editor to query AWS GlueData Catalog tables with data stored in Amazon Simple Storage Service (Amazon S3). User2 is a Data Engineer and uses Amazon EMR Studionotebooks to query Data Catalog tables and also query raw data stored in Amazon S3 that is not yet cataloged to the Data Catalog. User3 is a Business Analyst who needs to query data stored in Amazon Redshift tables using the Amazon Redshift Query Editor v2. Additionally, this user builds Amazon QuickSight visualizations for the data in Redshift tables.
OkTank wants to simplify governance by centralizing data access control for their variety of data sources, user identities, and tools. They also want to define permissions directly on their corporate user or group identities from Okta instead of creating IAM roles for each user and group and managing access on the IAM role. In addition, for their audit requirements, they need the capability to map data access to the corporate identity of users within Okta for enhanced tracking and accountability.
To achieve these goals, we use trusted identity propagation with the aforementioned services and use AWS Lake Formation and Amazon S3 Access Grants for access controls. We use Lake Formation to centrally manage permissions to the Data Catalog tables and Redshift tables shared with Redshift datashares. In our scenario, we use S3 Access Grants for granting permission for the Athena query result location. Additionally, we show how to access a raw data bucket governed by S3 Access Grants with an EMR notebook.
Data access is audited with AWS CloudTrail and can be queried with AWS CloudTrail Lake. This architecture showcases the versatility and effectiveness of AWS analytics services in enabling efficient and secure data analysis workflows across different use cases and user personas.
We use Okta as the external IdP, but you can also use other IdPs like Microsoft Azure Active Directory. Users and groups from Okta are synced to IAM Identity Center. In this post, we have three groups, as shown in the following diagram. User1 needs to query a Data Catalog table with data stored in Amazon S3. The S3 location is secured and managed by Lake Formation. The user connects to an IAM Identity Center enabled Athena workgroup using the Athena query editor with EMR Studio. The IAM Identity Center enabled Athena workgroups need to be secured with S3 Access Grants permissions for the Athena query results location. With this feature, you can also enable the creation of identity-based query result locations that are governed by S3 Access Grants. These user identity-based S3 prefixes let users in an Athena workgroup keep their query results isolated from other users in the same workgroup. The following diagram illustrates this architecture. User2 needs to query the same Data Catalog table as User1. This table is governed using Lake Formation permissions. Additionally, the user needs to access raw data in another S3 bucket that isn’t cataloged to the Data Catalog and is controlled using S3 Access Grants; in the following diagram, this is shown as S3 Data Location-2.
The user uses an EMR Studio notebook to run Spark queries on an EMR cluster. The EMR cluster uses a security configuration that integrates with IAM Identity Center for authentication and uses Lake Formation for authorization. The EMR cluster is also enabled for S3 Access Grants. With this kind of hybrid access management, you can use Lake Formation to centrally manage permissions for your datasets cataloged to the Data Catalog and use S3 Access Grants to centrally manage access to your raw data that is not yet cataloged to the Data Catalog. This gives you flexibility to access data managed by either of the access control mechanisms from the same notebook.
User3 uses the Redshift Query Editor V2 to query a Redshift table. The user also accesses the same table with QuickSight. For our demo, we use a single user persona for simplicity, but in reality, these could be completely different user personas. To enable access control with Lake Formation for Redshift tables, we use data sharing in Lake Formation.
Data access requests by the specific users are logged to CloudTrail. Later in this post, we also briefly touch upon using CloudTrail Lake to query the data access events.
In the following sections, we demonstrate how to build this architecture. We use AWS CloudFormation to provision the resources. AWS CloudFormation lets you model, provision, and manage AWS and third-party resources by treating infrastructure as code. We also use the AWS Command Line Interface (AWS CLI) and AWS Management Console to complete some steps.
The following diagram shows the end-to-end architecture.
Prerequisites
Complete the following prerequisite steps:
Have an AWS account. If you don’t have an account, you can create one.
Have IAM Identity Center set up in a specific AWS Region.
Make sure you use the same Region where you have IAM Identity Center set up throughout the setup and verification steps. In this post, we use the us-east-1 Region.
After the Okta groups are pushed to IAM Identity Center, you can see the users and groups on the IAM Identity Center console, as shown in the following screenshot. You need the group IDs of the three groups to be passed in the CloudFormation template.
For enabling User2 access using the EMR cluster, you need have an SSL certificate .zip file available in your S3 bucket. You can download the following sample certificate to use in this post. In production use cases, you should create and use your own certificates. You need to reference the bucket name and the certificate bundle .zip file in AWS CloudFormation. The CloudFormation template lets you choose the components you want to provision. If you do not intend to deploy the EMR cluster, you can ignore this step.
Have an administrator user or role to run the CloudFormation stack. The user or role should also be a Lake Formation administrator to grant permissions.
Deploy the CloudFormation stack
The CloudFormation template provided in the post lets you choose the components you want to provision from the solution architecture. In this post, we enable all components, as shown in the following screenshot. Run the provided CloudFormation stack to create the solution resources. Refer to the following table for a list of important parameters.
Parameter Group
Description
Parameter Name
Expected Value
Choose components to provision.
Choose the components you want to be provisioned.
DeployAthenaFlow
Yes/No. If you choose No, you can ignore the parameters in the “Athena Configuration” group.
DeployEMRFlow
Yes/No. If you choose No, you can ignore the parameters in the “EMR Configuration” group.
DeployRedshiftQEV2Flow
Yes/No. If you choose No, you can ignore the parameters in the “Redshift Configuration” group.
CreateS3AGInstance
Yes/No. If you already have an S3 Access Grants instance, choose No. Otherwise, choose Yes to allow the stack create a new S3 Access Grants instance. The S3 Access Grants instance is needed for User1 and User2.
Identity Center Configuration
IAM Identity Center parameters.
IDCGroup1Id
Group ID corresponding to Group1 from IAM Identity Center.
IDCGroup2Id
Group ID corresponding to Group2 from IAM Identity Center.
IDCGroup3Id
Group ID corresponding to Group3 from IAM Identity Center.
IAMIDCInstanceArn
IAM Identity Center instance ARN. You can get this from the Settings section of IAM Identity Center.
Redshift Configuration
Redshift parameters.
Ignore if you chose DeployRedshiftQEV2Flow as No.
RedshiftServerlessAdminUserName
Redshift admin user name.
RedshiftServerlessAdminPassword
Redshift admin password.
RedshiftServerlessDatabase
Redshift database to create the tables.
EMR Configuration
EMR parameters.
Ignore if you chose parameter DeployEMRFlow as No.
SSlCertsS3BucketName
Bucket name where you copied the SSL certificates.
SSlCertsZip
Name of SSL certificates file (my-certs.zip) to use the sample certificate provided in the post.
Athena Configuration
Athena parameters.
Ignore if you chose parameter DeployAthenaFlow as No.
IDCUser1Id
User ID corresponding to User1 from IAM Identity Center.
The CloudFormation stack provisions the following resources:
A VPC with a public and private subnet.
If you chose the Redshift components, it also creates three additional subnets.
S3 buckets for data and Athena query results location storage. It also copies some sample data to the buckets.
Registers the source S3 bucket with Lake Formation.
An AWS Glue database named oktank_tipblog_temp and a table named customer under the database. The table points to the Amazon S3 location governed by Lake Formation.
Allows external engines to access data in Amazon S3 locations with full table access. This is required for Amazon EMR integration with Lake Formation for trusted identity propagation. As of this writing, Amazon EMR supports table-level access with IAM Identity Center enabled clusters.
An S3 Access Grants instance.
S3 Access Grants for Group1 to the User1 prefix under the Athena query results location bucket.
S3 Access Grants for Group2 to the S3 bucket input and output prefixes. The user has read access to the input prefix and write access to the output prefix under the bucket.
An Amazon Redshift Serverless namespace and workgroup. This workgroup is not integrated with IAM Identity Center; we complete subsequent steps to enable IAM Identity Center for the workgroup.
An AWS Cloud9 integrated development environment (IDE), which we use to run AWS CLI commands during the setup.
Note the stack outputs on the AWS CloudFormation console. You use these values in later steps. Choose the link for Cloud9URL in the stack output to open the AWS Cloud9 IDE. In AWS Cloud9, go to the Window tab and choose New Terminal to start a new bash terminal.
Set up Lake Formation
You need to enable Lake Formation with IAM Identity Center and enable an EMR application with Lake Formation integration. Complete the following steps:
In the AWS Cloud9 bash terminal, enter the following command to get the Amazon EMR security configuration created by the stack:
Note the value for IdcApplicationARN from the output.
Enter the following command in AWS Cloud9 to enable the Lake Formation integration with IAM Identity Center and add the Amazon EMR security configuration application as a trusted application in Lake Formation. If you already have the IAM Identity Center integration with Lake Formation, sign in to Lake Formation and add the preceding value to the list of applications instead of running the following command and proceed to next step.
aws lakeformation create-lake-formation-identity-center-configuration --catalog-id <Replace with CatalogId value from Cloudformation output> --instance-arn <Replace with IDCInstanceARN value from CloudFormation stack output> --external-filtering Status=ENABLED,AuthorizedTargets=<Replace with IdcApplicationARN value copied in previous step>
After this step, you should see the application on the Lake Formation console. This completes the initial setup. In subsequent steps, we apply some additional configurations for specific user personas.
Validate user personas
To review the S3 Access Grants created by AWS CloudFormation, open the Amazon S3 console and Access Grants in the navigation pane. Choose the access grant you created to view its details.
The CloudFormation stack created the S3 Access Grants for Group1 for the User1 prefix under the Athena query results location bucket. This allows User1 to access the prefix under in the query results bucket. The stack also created the grants for Group2 for User2 to access the raw data bucket input and output prefixes.
Set up User1 access
Complete the steps in this section to set up User1 access.
Create an IAM Identity Center enabled Athena workgroup
Let’s create the Athena workgroup that will be used by User1.
Enter the following command in the AWS Cloud9 terminal. The command creates an IAM Identity Center integrated Athena workgroup and enables S3 Access Grants for the user-level prefix. These user identity-based S3 prefixes let users in an Athena workgroup keep their query results isolated from other users in the same workgroup. The prefix is automatically created by Athena when the CreateUserLevelPrefix option is enabled. Access to the prefix was granted by the CloudFormation stack.
aws athena create-work-group --cli-input-json '{
"Name": "AthenaIDCWG",
"Configuration": {
"ResultConfiguration": {
"OutputLocation": "<Replace with AthenaResultLocation from CloudFormation stack>"
},
"ExecutionRole": "<Replace with TIPStudioRoleArn from CloudFormation stack>",
"IdentityCenterConfiguration": {
"EnableIdentityCenter": true,
"IdentityCenterInstanceArn": "<Replace with IDCInstanceARN from CloudFormation stack>"
},
"QueryResultsS3AccessGrantsConfiguration": {
"EnableS3AccessGrants": true,
"CreateUserLevelPrefix": true,
"AuthenticationType": "DIRECTORY_IDENTITY"
},
"EnforceWorkGroupConfiguration":true
},
"Description": "Athena Workgroup with IDC integration"
}'
Grant access to User1 on the Athena workgroup
Sign in to the Athena console and grant access to Group1 to the workgroup as shown in the following screenshot. You can grant access to the user (User1) or to the group (Group1). In this post, we grant access to Group1.
Grant access to User1 in Lake Formation
Sign in to the Lake Formation console, choose Data lake permissions in the navigation pane, and grant access to the user group on the database oktank_tipblog_temp and table customer.
With Athena, you can grant access to specific columns and for specific rows with row-level filtering. For this post, we grant column-level access and restrict access to only selected columns for the table. This completes the access permission setup for User1.
Verify access
Let’s see how User1 uses Athena to analyze the data.
Copy the URL for EMRStudioURL from the CloudFormation stack output.
Open a new browser window and connect to the URL.
You will be redirected to the Okta login page.
Log in with User1.
In the EMR Studio query editor, change the workgroup to AthenaIDCWG and choose Acknowledge.
Run the following query in the query editor:
SELECT * FROM "oktank_tipblog_temp"."customer" limit 10;
You can see that the user is only able to access the columns for which permissions were previously granted in Lake Formation. This completes the access flow verification for User1.
Set up User2 access
User2 accesses the table using an EMR Studio notebook. Note the current considerations for EMR with IAM Identity Center integrations.
Complete the steps in this section to set up User2 access.
Grant Lake Formation permissions to User2
Sign in to the Lake Formation console and grant access to Group2 on the table, similar to the steps you followed earlier for User1. Also grant Describe permission on the default database to Group2, as shown in the following screenshot.
Copy the URL for EMR Studio from the EMRStudioURL value from the CloudFormation stack output.
Log in to EMR Studio as User2 on the Okta login page.
Create a Workspace, giving it a name and leaving all other options as default.
This will open a JupyterLab notebook in a new window.
Connect to the EMR Studio notebook
In the Compute pane of the notebook, select the EMR cluster (named EMRWithTIP) created by the CloudFormation stack to attach to it. After the notebook is attached to the cluster, choose the PySpark kernel to run Spark queries.
Verify access
Enter the following query in the notebook to read from the customer table:
spark.sql("select * from oktank_tipblog_temp.customer").show()
The user access works as expected based on the Lake Formation grants you provided earlier.
Run the following Spark query in the notebook to read data from the raw bucket. Access to this bucket is controlled by S3 Access Grants.
Let’s write this data to the same bucket and input prefix. This should fail because you only granted read access to the input prefix with S3 Access Grants.
Customer managed policy redshift-idc-policy-tip. This policy is already created by the CloudFormation stack, so you don’t have to create it.
Provide a name (tip-blog-qe-v2-permission-set) to the permission set.
Set the relay state as https://<region-id>.console.aws.amazon.com/sqlworkbench/home (for example, https://us-east-1.console.aws.amazon.com/sqlworkbench/home).
Choose Create.
Assign Group3 to the account in IAM Identity Center, select the permission set you created, and choose Submit.
Create the Redshift IAM Identity Center application
Enter the following in the AWS Cloud9 terminal:
aws redshift create-redshift-idc-application \
--idc-instance-arn '<Replace with IDCInstanceARN value from CloudFormation Output>' \
--redshift-idc-application-name 'redshift-iad-<Replace with CatalogId value from CloudFormation output>-tip-blog-1' \
--identity-namespace 'tipblogawsidc' \
--idc-display-name 'TIPBlog_AWSIDC' \
--iam-role-arn '<Replace with TIPRedshiftRoleArn value from CloudFormation output>' \
--service-integrations '[
  {
    "LakeFormation": [
    {
     "LakeFormationQuery": {
     "Authorization": "Enabled"
    }
   }
  ]
 }
]'
Enter the following command to get the application details:
Keep a note of the IdcManagedApplicationArn, IdcDisplayName, and IdentityNamespace values in the output for the application with IdcDisplayName TIPBlog_AWSIDC. You need these values in the next step.
Enable the Redshift Query Editor v2 for the Redshift IAM Identity Center application
Complete the following steps:
On the Amazon Redshift console, choose IAM Identity Center connections in the navigation pane.
Choose the application you created.
Choose Edit.
Select Enable Query Editor v2 application and choose Save changes.
On the Groups tab, choose Add or assign groups.
Assign Group3 to the application.
The Redshift IAM Identity Center connection is now set up.
Enable the Redshift Serverless namespace and workgroup with IAM Identity Center
The CloudFormation stack you deployed created a serverless namespace and workgroup. However, they’re not enabled with IAM Identity Center. To enable with IAM Identity Center, complete the following steps. You can get the namespace name from the RedshiftNamespace value of the CloudFormation stack output.
On the Amazon Redshift Serverless dashboard console, navigate to the namespace you created.
Choose Query Data to open Query Editor v2.
Choose the options menu (three dots) and choose Create connections for the workgroup redshift-idc-wg-tipblog.
Choose Other ways to connect and then Database user name and password.
Use the credentials you provided for the Redshift admin user name and password parameters when deploying the CloudFormation stack and create the connection.
Create resources using the Redshift Query Editor v2
You now enter a series of commands in the query editor with the database admin user.
Create an IdP for the Redshift IAM Identity Center application:
CREATE IDENTITY PROVIDER "TIPBlog_AWSIDC" TYPE AWSIDC
NAMESPACE 'tipblogawsidc'
APPLICATION_ARN '<Replace with IdcManagedApplicationArn value you copied earlier in Cloud9>'
IAM_ROLE '<Replace with TIPRedshiftRoleArn value from CloudFormation output>';
Enter the following command to check the IdP you added previously:
SELECT * FROM svv_identity_providers;
Next, you grant permissions to the IAM Identity Center user.
Create a role in Redshift. This role should correspond to the group in IAM Identity Center to which you intend to provide the permissions (Group3 in this post). The role should follow the format <namespace>:<GroupNameinIDC>.
Create role "tipblogawsidc:Group3";
Run the following command to see role you created. The external_id corresponds to the group ID value for Group3 in IAM Identity Center.
Select * from svv_roles where role_name = 'tipblogawsidc:Group3';
Create a sample table to use to verify access for the Group3 user:
CREATE TABLE IF NOT EXISTS revenue
(
account INTEGER ENCODE az64
,customer VARCHAR(20) ENCODE lzo
,salesamt NUMERIC(18,0) ENCODE az64
)
DISTSTYLE AUTO
;

insert into revenue values (10001, 'ABC Company', 12000);
insert into revenue values (10002, 'Tech Logistics', 175400);
Grant access to the user on the schema:
-- Grant usage on schema
grant usage on schema public to role "tipblogawsidc:Group3";
To create a datashare and add the preceding table to the datashare, enter the following statements:
CREATE DATASHARE demo_datashare;
ALTER DATASHARE demo_datashare ADD SCHEMA public;
ALTER DATASHARE demo_datashare ADD TABLE revenue;
Grant usage on the datashare to the account using the Data Catalog:
GRANT USAGE ON DATASHARE demo_datashare TO ACCOUNT '<Replace with CatalogId from Cloud Formation Output>' via DATA CATALOG;
Authorize the datashare
For this post, we use the AWS CLI to authorize the datashare. You can also do it from the Amazon Redshift console.
Enter the following command in the AWS Cloud9 IDE to describe the datashare you created and note the value of DataShareArn and ConsumerIdentifier to use in subsequent steps:
aws redshift describe-data-shares
Enter the following command in the AWS Cloud9 IDE to the authorize the datashare:
aws redshift authorize-data-share --data-share-arn <Replace with DataShareArn value copied from earlier command’s output> --consumer-identifier <Replace with ConsumerIdentifier value copied from earlier command’s output >
Accept the datashare in Lake Formation
Next, accept the datashare in Lake Formation.
On the Lake Formation console, choose Data sharing in the navigation pane.
In the Invitations section, select the datashare invitation that is pending acceptance.
Choose Review invitation and accept the datashare.
Provide a database name (tip-blog-redshift-ds-db), which will be created in the Data Catalog by Lake Formation.
Choose Skip to Review and Create and create the database.
Grant permissions in Lake Formation
Complete the following steps:
On the Lake Formation console, choose Data lake permissions in the navigation pane.
Choose Grant and in the Principals section, choose User3 to grant permissions with the IAM Identity Center-new option. Refer to the Lake Formation access grants steps performed for User1 and User2 if needed.
Choose the database (tip-blog-redshift-ds-db) you created earlier and the table public.revenue, which you created in the Redshift Query Editor v2.
For Table permissions¸ select Select.
For Data permissions¸ select Column-based access and select the account and salesamt columns.
Choose Grant.
Mount the AWS Glue database to Amazon Redshift
As the last step in the setup, mount the AWS Glue database to Amazon Redshift. In the Query Editor v2, enter the following statements:
create external schema if not exists tipblog_datashare_idc_schema from DATA CATALOG DATABASE 'tip-blog-redshift-ds-db' catalog_id '<Replace with CatalogId from CloudFormation output>';

grant usage on schema tipblog_datashare_idc_schema to role "tipblogawsidc:Group3";

grant select on all tables in schema tipblog_datashare_idc_schema to role "tipblogawsidc:Group3";
You are now done with the required setup and permissions for User3 on the Redshift table.
Verify access
To verify access, complete the following steps:
Get the AWS access portal URL from the IAM Identity Center Settings section.
Open a different browser and enter the access portal URL.
This will redirect you to your Okta login page.
Sign in, select the account, and choose the tip-blog-qe-v2-permission-set link to open the Query Editor v2.
If you’re using private or incognito mode for testing this, you may need to enable third-party cookies.
Choose the options menu (three dots) and choose Edit connection for the redshift-idc-wg-tipblog workgroup.
Use IAM Identity Center in the pop-up window and choose Continue.
If you get an error with the message “Redshift serverless cluster is auto paused,” switch to the other browser with admin credentials and run any sample queries to un-pause the cluster. Then switch back to this browser and continue the next steps.
Run the following query to access the table:
SELECT * FROM "dev"."tipblog_datashare_idc_schema"."public.revenue";
You can only see the two columns due to the access grants you provided in Lake Formation earlier.
This completes configuring User3 access to the Redshift table.
Set up QuickSight for User3
Let’s now set up QuickSight and verify access for User3. We already granted access to User3 to the Redshift table in earlier steps.
Choose Group3 for the author and reader for this post.
For IAM Role, choose the IAM role matching the RoleQuickSight value from the CloudFormation stack output.
Next, you add a VPC connection to QuickSight to access the Redshift Serverless namespace you created earlier.
On the QuickSight console, manage your VPC connections.
Choose Add VPC connection.
For VPC connection name, enter a name.
For VPC ID, enter the value for VPCId from the CloudFormation stack output.
For Execution role, choose the value for RoleQuickSight from the CloudFormation stack output.
For Security Group IDs, choose the security group for QSSecurityGroup from the CloudFormation stack output.
Wait for the VPC connection to be AVAILABLE.
Enter the following command in AWS Cloud9 to enable QuickSight with Amazon Redshift for trusted identity propagation:
aws quicksight update-identity-propagation-config --aws-account-id "<Replace with CatalogId from CloudFormation output>" --service "REDSHIFT" --authorized-targets "< Replace with IdcManagedApplicationArn value from output of aws redshift describe-redshift-idc-applications --output json which you copied earlier>"
Verify User3 access with QuickSight
Complete the following steps:
Sign in to the QuickSight console as User3 in a different browser.
On the Okta sign-in page, sign in as User 3.
Create a new dataset with Amazon Redshift as the data source.
Choose the VPC connection you created above for Connection Type.
Provide the Redshift server (the RedshiftSrverlessWorkgroup value from the CloudFormation stack output), port (5439 in this post), and database name (dev in this post).
Under Authentication method, select Single sign-on.
Choose Validate, then choose Create data source.
If you encounter an issue with validating using single sign-on, switch to Database username and password for Authentication method, validate with any dummy user and password, and then switch back to validate using single sign-on and proceed to the next step. Also check that the Redshift serverless cluster is not auto-paused as mentioned earlier in Redshift access verification.
Choose the schema you created earlier (tipblog_datashare_idc_schema) and the table public.revenue
Choose Select to create your dataset.
You should now be able to visualize the data in QuickSight. You are only able to only see the account and salesamt columns from the table because of the access permissions you granted earlier with Lake Formation.
This finishes all the steps for setting up trusted identity propagation.
Audit data access
Let’s see how we can audit the data access with the different users.
Access requests are logged to CloudTrail. The IAM Identity Center user ID is logged under the onBehalfOf tag in the CloudTrail event. The following screenshot shows the GetDataAccess event generated by Lake Formation. You can view the CloudTrail event history and filter by event name GetDataAccess to view similar events in your account. You can see the userId corresponds to User2.
You can run the following commands in AWS Cloud9 to confirm this.
Get the identity store ID:
aws sso-admin describe-instance --instance-arn <Replace with your instance arn value> | jq -r '.IdentityStoreId'
Describe the user in the identity store:
aws identitystore describe-user --identity-store-id <Replace with output of above command> --user-id <User Id from above screenshot>
One way to query the CloudTrail log events is by using CloudTrail Lake. Set up the event data store (refer to the following instructions) and rerun the queries for User1, User2, and User3. You can query the access events using CloudTrail Lake with the following sample query:
SELECT eventTime,userIdentity.onBehalfOf.userid AS idcUserId,requestParameters as accessInfo, serviceEventDetails
FROM 04d81d04-753f-42e0-a31f-2810659d9c27
WHERE userIdentity.arn IS NOT NULL AND eventName='BatchGetTable' or eventName='GetDataAccess' or eventName='CreateDataSet'
order by eventTime DESC
The following screenshot shows an example of the detailed results with audit explanations.
Clean up
To avoid incurring further charges, delete the CloudFormation stack. Before you delete the CloudFormation stack, delete all the resources you created using the console or AWS CLI:
Manually delete any EMR Studio Workspaces you created with User2.
Delete the Athena workgroup created as part of the User1 setup.
Delete the QuickSight VPC connection you created.
Delete the Redshift IAM Identity Center connection.
Deregister IAM Identity Center from S3 Access Grants.
Delete the CloudFormation stack.
Manually delete the VPC created by AWS CloudFormation.
Conclusion
In this post, we delved into the trusted identity propagation feature of AWS Identity Center alongside various AWS Analytics services, demonstrating its utility in managing permissions using corporate user or group identities rather than IAM roles. We examined diverse user personas utilizing interactive tools like Athena, EMR Studio notebooks, Redshift Query Editor V2, and QuickSight, all centralized under Lake Formation for streamlined permission management. Additionally, we explored S3 Access Grants for S3 bucket access management, and concluded with insights into auditing through CloudTrail events and CloudTrail Lake for a comprehensive overview of user data access.
For further reading, refer to the following resources:
Shoukat Ghouse is a Senior Big Data Specialist Solutions Architect at AWS. He helps customers around the world build robust, efficient and scalable data platforms on AWS leveraging AWS analytics services like AWS Glue, AWS Lake Formation, Amazon Athena and Amazon EMR.
Amazon Pinpoint customers who use campaigns, journeys, or the SendMesages API to send more than 5,000 marketing email messages per day are considered “bulk senders”. If your organization meets this criteria, you are now subject to new requirements that were recently established by Google, Yahoo and other large ISPs/ESPs. These providers have mandated these requirements to help protect their user’s inboxes. Detailed information about these requirements is provided in the Amazon Simple Email Service (SES) bulk sender updates blog post.
Per these new requirements, Pinpoint customers that send marketing email messages in bulk must meet all of these criteria:
Fully authenticate their email sending domains with SPF, DKIM and DMARC. See this blog.
Provide a clearly visible unsubscribe link in the body &/or footer of each message.
Enable the “List-Unsubscribe” and “List-Unsubscribe-Post” one-click unsubscribe (the subbect of this blog post). You can learn more about these headers and how they are used in SES in this related blog post.
Honor all unsubscribe POST requests within 48 hours, after which time you shouldn’t be sending emails to the now unsubscribed end-user.
Actively monitor spam complaint rates, and take the steps needed to ensure these rates remain below acceptable levels as defined by the ESPs.
This blog post provides Pinpoint customers with the steps necessary to enable the one-click unsubscribe button via email headers for “List-Unsubscribe” and “List-Unsubscribe-Post” as defined by RFC 2369 and RFC 8058.
Unsubscribe Process Overview
Pinpoint now supports the inclusion of the “List-Unsubscribe” and “List-Unsubscribe-Post” email headers that enable compatible email client apps to render a one-click unsubscribe button when displaying emails from a subscription list. When you include these headers in the emails you send by Pinpoint, those end-users who want to unsubscribe from your emails can do so by simply clicking the unsubscribe button in their email app (see image). Once pressed, the unsubscribe button fires off a POST request to the URL you have defined in the “List-Unsubscribe” header.
You, the Pinpoint customer, are responsible for defining the “List-Unsubscribe” and “List-Unsubscribe-Post” headers, as well as supplying the system or process invoked by the “List-Unsubscribe” and “List-Unsubscribe-Post” email headers. Your system or process must, when activated by the unsubscribe action, update that end-user’s preferences accordingly so that within 48 hours, any end-user who unsubscribes will no longer receive unwanted emails.
If you only use Pinpoint’s campaigns and journeys, you may elect to use the Pinpoint endpoint’s OptOut attribute to store the user’s unsubscribe preferences. Possible values for OptOut are: ALL, the user has opted out and doesn’t want to receive any messages; and, NONE, the user hasn’t opted out and wants to receive all messages. It is important to note, however, that the SendMessages API ignores the Pinpoint endpoint’s OptOut attribute.
If you do not currently offer your recipients the option to unsubscribe to unwanted emails, you will need to develop & deploy a system or process to receive end-user unsubscribe requests to be in compliance with these new requirements. An example solution with sample code to processes email opt-out requests for Pinpoint can be found here. You can read more about this example in this blog post.
REQUIRED: Update the SES IAM role used by Pinpoint
Because Pinpoint uses SES resources for sending email messages, when using campaigns or journeys you must now create (or update) an IAM Orchestration sending role to grant Pinpoint service access to your SES resources. This allows Pinpoint to send emails via SES. To add or update the IAM role, follow the steps outlined in the Pinpoint documentation.
Note – If you are sending emails directly via the SendMesage, API you do not need an IAM Orchestration sending role, but you must have permissions for ses:SendEmail and ses:SendRawEmail.
Add easy unsubscribe email headers:
The steps you need to take to enable one-click unsubscribe in your Pinpoint emails depends on how you send emails, and whether or not you use templates, as shown below:
Use SendMessages with the AWS SDK or CLI
Using the AWS CLI: add headers for the “List-Unsubscribe” and “List-Unsubscribe-post” as shown in the example below:
Below is an example using the SendMessages API from the AWS SDK for Python (Boto3) that includes the List-Unsubscribe headers. This example assumes that you’ve already installed and updated the SDK for Python (Boto3) to the latest version available. For more information, see Quickstart in the AWS SDK for Python (Boto3) API Reference.
import logging  # Logging library to log messages
import boto3  # AWS SDK for Python
from botocore.exceptions import ClientError  # Exception handling for boto3
import hashlib  # Library to generate unique hashes

# Configure logger
logger = logging.getLogger(__name__)

# Define constants
CHARSET = "UTF-8"
REGION = 'us-east-1'

def send_email_message(
    pinpoint_client,
    project_id,
    sender,
    to_addresses,
    subject,
    html_message,
    text_message,
):
    """
    Sends an email message with HTML and plain text versions.

    :param pinpoint_client: A Boto3 Pinpoint client.
    :param project_id: The Amazon Pinpoint project ID to use when you send this message.
    :param sender: The "From" address. This address must be verified in
                   Amazon Pinpoint in the AWS Region you're using to send email.
    :param to_addresses: The list of addresses on the "To" line. If your Amazon Pinpoint account
                         is in the sandbox, these addresses must be verified.
    :param subject: The subject line of the email.
    :param html_message: The HTML content of the email.
    :param text_message: The plain text content of the email.
    :return: A dict of to_addresses and their message IDs.
    """
    try:
        # Create a dictionary of addresses with unique unsubscribe URLs
        # The addresses are encoded using the SHA256 hashing algorithm from the hashlib library
        # to create a unique and obfuscated unsubscribe URL for each recipient. This ensures
        # that the unsubscribe link is specific to each individual recipient, preventing
        # potential abuse or unauthorized unsubscribes. The hashed value is appended to the
        # base unsubscribe URL, allowing the email service to identify the intended recipient
        # when the unsubscribe link is clicked, while also protecting the recipient's personal
        # email address from being directly exposed in the URL.
        addresses = {
            address: {
                "ChannelType": "EMAIL",
                "Substitutions": {
                    "unsubscribeURL": [f"https://example.com/unsub/{hashlib.sha256(address.encode()).hexdigest()}"],
                }
            }
            for address in to_addresses
        }

        # Send email using Amazon Pinpoint
        response = pinpoint_client.send_messages(
            ApplicationId=project_id,
            MessageRequest={
                "Addresses": addresses,
                "MessageConfiguration": {
                    "EmailMessage": {
                        "FromAddress": sender,
                        "SimpleEmail": {
                            "Subject": {"Charset": CHARSET, "Data": subject},
                            "HtmlPart": {"Charset": CHARSET, "Data": html_message},
                            "TextPart": {"Charset": CHARSET, "Data": text_message},
                            "Headers": [
                                {"Name": "List-Unsubscribe", "Value": "{{unsubscribeURL}}"},
                                {"Name": "List-Unsubscribe-Post", "Value": "List-Unsubscribe=One-Click"}
                            ],
                        },
                    }
                }
            }
        )
    except ClientError as e:
        # Log exception if sending email fails
        logger.exception("Couldn't send email: %s", e)
        raise
    else:
        # Return a dictionary of addresses and their respective message IDs
        return {
            address: message["MessageId"]
        for address, message in response["MessageResponse"]["Result"].items()
        }

def main():
    # Sample data for sending email
    project_id = "ce796be37f32f178af652b26eexample"  # Amazon Pinpoint project ID
    sender = "[email protected]"  # Verified sender email address
    to_addresses = ["[email protected]", "[email protected]", "[email protected]"]  # Recipient email addresses
    subject = "Amazon Pinpoint Unsubscribe Headers Test (SDK for Python (Boto3))"  # Email subject
    text_message = """Amazon Pinpoint Test (SDK for Python)
    -------------------------------------
    This email was sent with Amazon Pinpoint using the AWS SDK for Python (Boto3).
    For more information, see https://aws.amazon.com/sdk-for-python/
                """  # Plain text message
    html_message = """<html>
    <head></head>
    <body>
      <h1>Amazon Pinpoint Test (SDK for Python (Boto3)</h1>
      <p>This email was sent with
        <a href='https://aws.amazon.com/pinpoint/'>Amazon Pinpoint</a> using the
        <a href='https://aws.amazon.com/sdk-for-python/'>
          AWS SDK for Python (Boto3)</a>.</p>
    </body>
    </html>
                """  # HTML message

    # Create a Pinpoint client
    pinpoint_client = boto3.client("pinpoint", region_name=REGION)

    print("Sending email.")
    # Send email and print message IDs
    try:
        message_ids = send_email_message(
            pinpoint_client,
            project_id,
            sender,
            to_addresses,
            subject,
            html_message,
            text_message,
        )
        print(f"Message sent! Message IDs: {message_ids}")
    except ClientError as e:
        print(f"Failed to send messages: {e}")

# Entry point of the script
if __name__ == "__main__":
    logging.basicConfig(level=logging.INFO)  # Set logging level to INFO
    main()
Send an email message with an existing email template.
If you use message templates to send email messages via AWS SDK for Python (Boto3), you can add the headers for List-Unsubscribe and List-Unsubscribe-post into the template, and then fill those variables with unique values per recipient, as shown in the code example below. First, you would create the template via the UI and add the Headers in the new fields as shown in the image below.
Or you can create the template, with headers, via the AWS CLI:
aws pinpoint create-email-template --template-name MyEmailTemplate \
--email-template-request '{
    "Subject": "Amazon Pinpoint Unsubscribe Headers Test using email template",
    "TextPart": "Hello, welcome to our service. We are glad to have you with us. If you wish to unsubscribe, click here: {{unsubscribeURL}}",
    "HtmlPart": "<html><body><h1>Hello, welcome to our service</h1><p>We are glad to have you with us.</p><p>If you wish to unsubscribe, click <a href=\"{{unsubscribeURL}}\">here</a>.</p></body></html>",
    "DefaultSubstitutions": "{\"unsubscribeURL\": \"https://example.com/unsubscribe\"}",
    "Headers": [
            {"Name": "List-Unsubscribe","Value": "{{unsubscribeURL}}"},
            {"Name": "List-Unsubscribe-Post","Value": "List-Unsubscribe=One-Click"}
        ]
  }
In this next example, we are including the use of a secret Hash key. By using this format, the unsubscribe URL will include the Pinpoint project ID and a hashed value of the email address combined with the secret key. This provides a more secure and customized unsubscribe experience for the recipients.
import logging  # Logging library to log messages
import boto3  # AWS SDK for Python
from botocore.exceptions import ClientError  # Exception handling for boto3
import hashlib  # Library to generate unique hashes

# Configure logger
logger = logging.getLogger(__name__)

# Define constants
REGION = 'us-east-1'
HASH_SECRET_KEY = "my_secret_key"  # Replace with your secret key

def send_templated_email_message(
    pinpoint_client,
    project_id,
    sender,
    to_addresses,
    template_name,
    template_version
):
    """
    Sends an email message with HTML and plain text versions.

    :param pinpoint_client: A Boto3 Pinpoint client.
    :param project_id: The Amazon Pinpoint project ID to use when you send this message.
    :param sender: The "From" address. This address must be verified in
                   Amazon Pinpoint in the AWS Region you're using to send email.
    :param to_addresses: The list of addresses on the "To" line. If your Amazon Pinpoint account
                         is in the sandbox, these addresses must be verified.
    :param template_name: The name of the email template to use when sending the message.
    :param template_version: The version number of the message template.

    :return: A dict of to_addresses and their message IDs.
    """
    try:
        # Create a dictionary of addresses with unique unsubscribe URLs
        # The addresses are encoded using the SHA256 hashing algorithm from the hashlib library
        # to create a unique and obfuscated unsubscribe URL for each recipient. This ensures
        # that the unsubscribe link is specific to each individual recipient, preventing
        # potential abuse or unauthorized unsubscribes. The hashed value is appended to the
        # base unsubscribe URL, allowing the email service to identify the intended recipient
        # when the unsubscribe link is clicked, while also protecting the recipient's personal
        # email address from being directly exposed in the URL.
        addresses = {
            address: {
                "ChannelType": "EMAIL",
                "Substitutions": {
                    "unsubscribeURL": [
                        f"https://www.example.com/preferences/index.html?pid={project_id}&h={hashlib.sha256((address + HASH_SECRET_KEY).encode()).hexdigest()}"
                    ]
                }
            }
            for address in to_addresses
        }
        # Send templated email using Amazon Pinpoint
        response = pinpoint_client.send_messages(
            ApplicationId=project_id,
            MessageRequest={
                "Addresses": addresses,
                "MessageConfiguration": {"EmailMessage": {"FromAddress": sender}},
                "TemplateConfiguration": {
                    "EmailTemplate": {
                        "Name": template_name,
                        "Version": template_version,
                    },
                },
            },
        )
    except ClientError as e:
        # Log exception if sending email fails
        logger.exception("Couldn't send email: %s", e)
        raise
    else:
        # Return a dictionary of addresses and their respective message IDs
        return {
            address: message["MessageId"]
        for address, message in response["MessageResponse"]["Result"].items()
        }


def main():
    # Sample data for sending email
    project_id = "ce796be37f32f178af652b26eexample"  # Amazon Pinpoint project ID
    sender = "[email protected]"  # Verified sender email address
    to_addresses = ["[email protected]", "[email protected]", "[email protected]"]  # Recipient email addresses
    template_name = "MyEmailTemplate"
    template_version = "1"

    # Create a Pinpoint client
    pinpoint_client = boto3.client("pinpoint", region_name=REGION)
    print("Sending email.")
    # Send email and print message IDs
    try:
        message_ids = send_templated_email_message(
            pinpoint_client,
            project_id,
            sender,
            to_addresses,
            template_name,
            template_version,
        ),
        print(f"Message sent! Message IDs: {message_ids}"),
    except ClientError as e:
        print(f"Failed to send messages: {e}")

# Entry point of the script
if __name__ == "__main__":
    logging.basicConfig(level=logging.INFO)  # Set logging level to INFO
    main()
Pinpoint Campaigns via API (runtime).
If you send emails using Pinpoint campaigns via the API call (runtime), you can add the headers as described below:
The Pinpoint console enables you to create (or update) your email templates to add support for up to 15 different headers, including the “List-Unsubscribe” and “List-Unsubscribe-Post” headers. Simply open , or create a new, template in the Pinpoint console, scroll to the bottom of the visual message editor, expand the Headers option, and insert the header names and values. Note that if you only use the console UI to send your Campaigns and Journeys, you can store the encoded List-Unsubscribe URL as an attribute in the endpoint, then use that attribute as the value as shown below:
Conclusion.
In this blog, we provide Pinpoint customers with the information and guidance needed to enable a one-click unsubscribe link in their recipients’ compatible email apps via “List-Unsubscribe” and “List-Unsubscribe-Post” email headers. Following this guidance, in conjunction with properly authenticating your email sending domains and monitoring / keeping spam complaints below prescribed thresholds will help ensure high rates of Pinpoint email deliverability.
We welcome your comments on this post below. For additional information, refer to these resources, or contact your AWS account team.
Zip is an Amazon Pinpoint and Amazon Simple Email Service Sr. Specialist Solutions Architect at AWS. Outside of work he enjoys time with his family, cooking, mountain biking and plogging.
Darren Roback
Darren is a Senior Solutions Architect with Amazon Web Services based in St. Louis, Missouri. He has a background in Security and Compliance, Serverless Event-Driven Architecture, and Enterprise Architecture. At AWS, Darren partners with customers to help them solve business challenges with AWS technology. Outside of work, Darren enjoys spending time in his shop working on woodworking projects.
Bruno Giorgini
Bruno Giorgini is a Senior Solutions Architect specializing in Pinpoint and SES. With over two decades of experience in the IT industry, Bruno has been dedicated to assisting customers of all sizes in achieving their objectives. When he is not crafting innovative solutions for clients, Bruno enjoys spending quality time with his wife and son, exploring the scenic hiking trails around the SF Bay Area.
AWS recently announced that Apache Flink is generally available for Amazon EMR on Amazon Elastic Kubernetes Service (EKS). Apache Flink is a scalable, reliable, and efficient data processing framework that handles real-time streaming and batch workloads (but is most commonly used for real-time streaming). Amazon EMR on EKS is a deployment option for Amazon EMR that allows you to run open source big data frameworks such as Apache Spark and Flink on Amazon Elastic Kubernetes Service (Amazon EKS) clusters with the EMR runtime. With the addition of Flink support in EMR on EKS, you can now run your Flink applications on Amazon EKS using the EMR runtime and benefit from both services to deploy, scale, and operate Flink applications more efficiently and securely.
In this post, we introduce the features of EMR on EKS with Apache Flink, discuss their benefits, and highlight how to get started.
EMR on EKS for data workloads
AWS customers deploying large-scale data workloads are adopting the EMR runtime with Amazon EKS as the underlying orchestrator to benefit from complimenting features. This also enables multi-tenancy and allows data engineers and data scientists to focus on building the data applications, and the platform engineering and the site reliability engineering (SRE) team can manage the infrastructure. Some key benefits of Amazon EKS for these customers are:
The AWS-managed control plane, which improves resiliency and removes undifferentiated heavy lifting
Features like multi-tenancy and resource-based access policies (RBAC), which allow you to build cost-efficient platforms and enforce organization-wide governance policies
The extensibility of Kubernetes, which allows you to install open source add-ons (observability, security, notebooks) to meet your specific needs
The EMR runtime offers the following benefits:
Takes care of the undifferentiated heavy lifting of managing installations, configuration, patching, and backups
Simplifies scaling
Optimizes performance and cost
Implements security and compliance by integrating with other AWS services and tools
Benefits of EMR on EKS with Apache Flink
The flexibility to choose instance types, price, and AWS Region and Availability Zone according to the workload specification is often the main driver of reliability, availability, and cost-optimization. Amazon EMR on EKS natively integrates tools and functionalities to enable these—and more.
Integration with existing tools and processes, such as continuous integration and continuous development (CI/CD), observability, and governance policies, helps unify the tools used and decreases the time to launch new services. Many customers already have these tools and processes for their Amazon EKS infrastructure, which you can now easily extend to your Flink applications running on EMR on EKS. If you’re interested in building your Kubernetes and Amazon EKS capabilities, we recommend using EKS Blueprints, which provides a starting place to compose complete EKS clusters that are bootstrapped with the operational software that is needed to deploy and operate workloads.
Another benefit of running Flink applications with Amazon EMR on EKS is improving your applications’ scalability. The volume and complexity of data processed by Flink apps can vary significantly based on factors like the time of the day, day of the week, seasonality, or being tied to a specific marketing campaign or other activity. This volatility makes customers trade off between over-provisioning, which leads to inefficient resource usage and higher costs, or under-provisioning, where you risk missing latency and throughput SLAs or even service outages. When running Flink applications with Amazon EMR on EKS, the Flink auto scaler will increase the applications’ parallelism based on the data being ingested, and Amazon EKS auto scaling with Karpenter or Cluster Autoscaler will scale the underlying capacity required to meet those demands. In addition to scaling up, Amazon EKS can also scale your applications down when the resources aren’t needed so your Flink apps are more cost-efficient.
Running EMR on EKS with Flink allows you to run multiple versions of Flink on the same cluster. With traditional Amazon Elastic Compute Cloud (Amazon EC2) instances, each version of Flink needs to run on its own virtual machine to avoid challenges with resource management or conflicting dependencies and environment variables. However, containerizing Flink applications allows you to isolate versions and avoid conflicting dependencies, and running them on Amazon EKS allows you to use Kubernetes as the unified resource manager. This means that you have the flexibility to choose which version of Flink is best suited for each job, and also improves your agility to upgrade a single job to the next version of Flink rather than having to upgrade an entire cluster, or spin up a dedicated EC2 instance for a different Flink version, which would increase your costs.
Key EMR on EKS differentiations
In this section, we discuss the key EMR on EKS differentiations.
Faster restart of the Flink job during scaling or failure recovery
This is enabled by task local recovery via Amazon Elastic Block Store (Amazon EBS) volumes and fine-grained recovery support in Adaptive Scheduler.
Task local recovery via EBS volumes for TaskManager pods is available with Amazon EMR 6.15.0 and higher. The default overlay mount comes with 10 GB, which is sufficient for jobs with a lower state. Jobs with large states can enable the automatic EBS volume mount option. The TaskManager pods are automatically created and mounted during pod creation and removed during pod deletion.
Fine-grained recovery support in the adaptive scheduler is available with Amazon EMR 6.15.0 and higher. When a task fails during its run, fine-grained recovery restarts only the pipeline-connected component of the failed task, instead of resetting the entire graph, and triggers a complete rerun from the last completed checkpoint, which is more expensive than just rerunning the failed tasks. To enable fine-grained recovery, set the following configurations in your Flink configuration:
jobmanager.execution.failover-strategy: region
restart-strategy: exponential-delay or fixed-delay
Logging and monitoring support with customer managed keys
Monitoring and observability are key constructs of the AWS Well-Architected framework because they help you learn, measure, and adapt to operational changes. You can enable monitoring of launched Flink jobs while using EMR on EKS with Apache Flink. Amazon Managed Service for Prometheus is deployed automatically, if enabled while installing the Flink operator, and it helps analyze Prometheus metrics emitted for the Flink operator, job, and TaskManager.
You can use the Flink UI to monitor health and performance of Flink jobs through a browser using port-forwarding. We have also enabled collection and archival of operator and application logs to Amazon Simple Storage Service (Amazon S3) or Amazon CloudWatch using a FluentD sidecar. This can be enabled through a monitoringConfiguration block in the deployment customer resource definition (CRD):
monitoringConfiguration:
    s3MonitoringConfiguration:
      logUri: S3 BUCKET
      encryptionKeyArn: CMK ARN FOR S3 BUCKET ENCRYPTION
    cloudWatchMonitoringConfiguration:
      logGroupName: LOG GROUP NAME
      logStreamNamePrefix: LOG GROUP STREAM PREFIX
    sideCarResources:
      limits:
        cpuLimit: 500m
        memoryLimit: 250Mi
    containerLogRotationConfiguration:
        rotationSize: 2Gb
        maxFilesToKeep: 10
Cost-optimization using Amazon EC2 Spot Instances
Amazon EC2 Spot Instances are an Amazon EC2 pricing option that provides steep discounts of up to 90% over On-Demand prices. It’s the preferred choice to run big data workloads because it helps improve throughput and optimize Amazon EC2 spend. Spot Instances are spare EC2 capacity and can be interrupted with notification if Amazon EC2 needs the capacity for On-Demand requests. Flink streaming jobs running on EMR on EKS can now respond to Spot Instance interruption, perform a just-in-time (JIT) checkpoint of the running jobs, and prevent scheduling further tasks on these Spot Instances. When restarting the job, not only will the job restart from the checkpoint, but a combined restart mechanism will provide a best-effort service to restart the job either after reaching target resource parallelism or the end of the current configured window. This can also prevent consecutive job restarts caused by Spot Instances stopping in a short interval and help reduce cost and improve performance.
To minimize the impact of Spot Instance interruptions, you should adopt Spot Instance best practices. The combined restart mechanism and JIT checkpoint is offered only in Adaptive Scheduler.
Integration with the AWS Glue Data Catalog as a metadata store for Flink applications
The AWS Glue Data Catalog is a centralized metadata repository for data assets across various data sources, and provides a unified interface to store and query information about data formats, schemas, and sources. Amazon EMR on EKS with Apache Flink releases 6.15.0 and higher support using the Data Catalog as a metadata store for streaming and batch SQL workflows. This further enables data understanding and makes sure that it is transformed correctly.
Integration with Amazon S3, enabling resiliency and operational efficiency
Amazon S3 is the preferred cloud object store for AWS customers to store not only data but also application JARs and scripts. EMR on EKS with Apache Flink can fetch application JARs and scripts (PyFlink) through deployment specification, which eliminates the need to build custom images in Flink’s Application Mode. When checkpointing on Amazon S3 is enabled, a managed state is persisted to provide consistent recovery in case of failures. Retrieval and storage of files using Amazon S3 is enabled by two different Flink connectors. We recommend using Presto S3 (s3p) for checkpointing and s3 or s3a for reading and writing files including JARs and scripts. See the following code:
...
spec:
  flinkConfiguration:
    taskmanager.numberOfTaskSlots: "2"
    state.checkpoints.dir: s3p://<BUCKET-NAME>/flink-checkpoint/
...
job:
jarURI: "s3://<S3-BUCKET>/scripts/pyflink.py" # Note, this will trigger the artifact download process
entryClass: "org.apache.flink.client.python.PythonDriver"
...
Role-based access control using IRSA
IAM Roles for Service Accounts (IRSA) is the recommended way to implement role-based access control (RBAC) for deploying and running applications on Amazon EKS. EMR on EKS with Apache Flink creates two roles (IRSA) by default for Flink operator and Flink jobs. The operator role is used for JobManager and Flink services, and the job role is used for TaskManagers and ConfigMaps. This helps limit the scope of AWS Identity and Access Management (IAM) permission to a service account, helps with credential isolation, and improves auditability.
Get started with EMR on EKS with Apache Flink
If you want to run a Flink application on recently launched EMR on EKS with Apache Flink, refer to Running Flink jobs with Amazon EMR on EKS, which provides step-by-step guidance to deploy, run, and monitor Flink jobs.
We have also created an IaC (Infrastructure as Code) template for EMR on EKS with Flink Streaming as part of Data on EKS (DoEKS), an open-source project aimed at streamlining and accelerating the process of building, deploying, and scaling data and ML workloads on Amazon Elastic Kubernetes Service (Amazon EKS). This template will help you to provision a EMR on EKS with Flink cluster and evaluate the features as mentioned in this blog. This template comes with the best practices built in, so you can use this IaC template as a foundation for deploying EMR on EKS with Flink in your own environment if you decide to use it as part of your application.
Conclusion
In this post, we explored the features of recently launched EMR on EKS with Flink to help you understand how you might run Flink workloads on a managed, scalable, resilient, and cost-optimized EMR on EKS cluster. If you are planning to run/explore Flink workloads on Kubernetes consider running them on EMR on EKS with Apache Flink. Please do contact your AWS Solution Architects, who can be of assistance alongside your innovation journey.
About the Authors
Kinnar Kumar Sen is a Sr. Solutions Architect at Amazon Web Services (AWS) focusing on Flexible Compute. As a part of the EC2 Flexible Compute team, he works with customers to guide them to the most elastic and efficient compute options that are suitable for their workload running on AWS. Kinnar has more than 15 years of industry experience working in research, consultancy, engineering, and architecture.
Alex Lines is a Principal Containers Specialist at AWS helping customers modernize their Data and ML applications on Amazon EKS.
Mengfei Wang is a Software Development Engineer specializing in building large-scale, robust software infrastructure to support big data demands on containers and Kubernetes within the EMR on EKS team. Beyond work, Mengfei is an enthusiastic snowboarder and a passionate home cook.
Jerry Zhang is a Software Development Manager in AWS EMR on EKS. His team focuses on helping AWS customers to solve their business problems using cutting-edge data analytics technology on AWS infrastructure.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.


 Figure 3: Configure domain
 Figure 4: Create a CloudFormation stack
 Figure 5: Set permissions in OpenSearch dashboards security plugin
 Figure 6: CloudFormation stack outputs


 ML-powered search with OpenSearch and set up you multimodal search solution in your own environment using the guidelines in this post. The solution code is also available on the GitHub repo.
 Praveen Mohan Prasad is an Analytics Specialist Technical Account Manager at Amazon Web Services and helps customers with pro-active operational reviews on analytics workloads. Praveen actively researches on applying machine learning to improve search relevance.
 Hajer Bouafif is an Analytics Specialist Solutions Architect at Amazon Web Services. She focuses on Amazon OpenSearch Service and helps customers design and build well-architected analytics workloads in diverse industries. Hajer enjoys spending time outdoors and discovering new cultures.
 Aruna Govindaraju is an Amazon OpenSearch Specialist Solutions Architect and has worked with many commercial and open-source search engines. She is passionate about search, relevancy, and user experience. Her expertise with correlating end-user signals with search engine behavior has helped many customers improve their search experience. Her favourite pastime is hiking the New England trails and mountains.


 Chandan Rupakheti is a Senior Solutions Architect at AWS. His main focus at AWS lies in the intersection of Analytics, Serverless, and AdTech services. He is a passionate technical leader, researcher, and mentor with a knack for building innovative solutions in the cloud. Outside of his professional life, he loves spending time with his family and friends besides listening and playing music.
 Parnab Basak is a Senior Solutions Architect and a Serverless Specialist at AWS. He specializes in creating new solutions that are cloud native using modern software development practices like serverless, DevOps, and analytics. Parnab works closely in the analytics and integration services space helping customers adopt AWS services for their workflow orchestration needs.

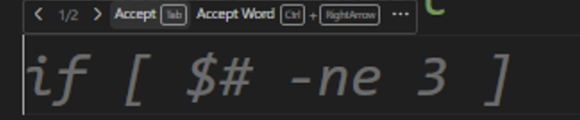
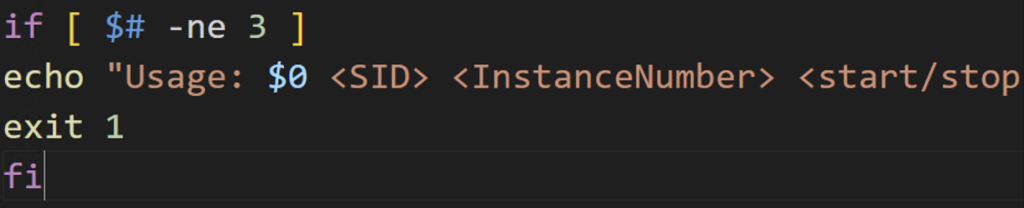
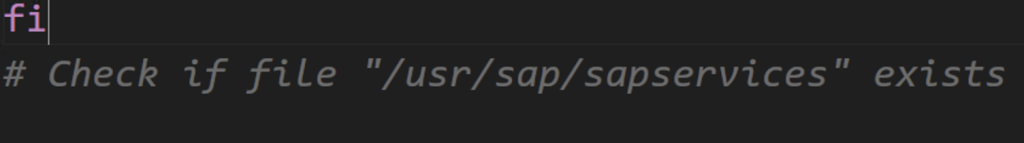
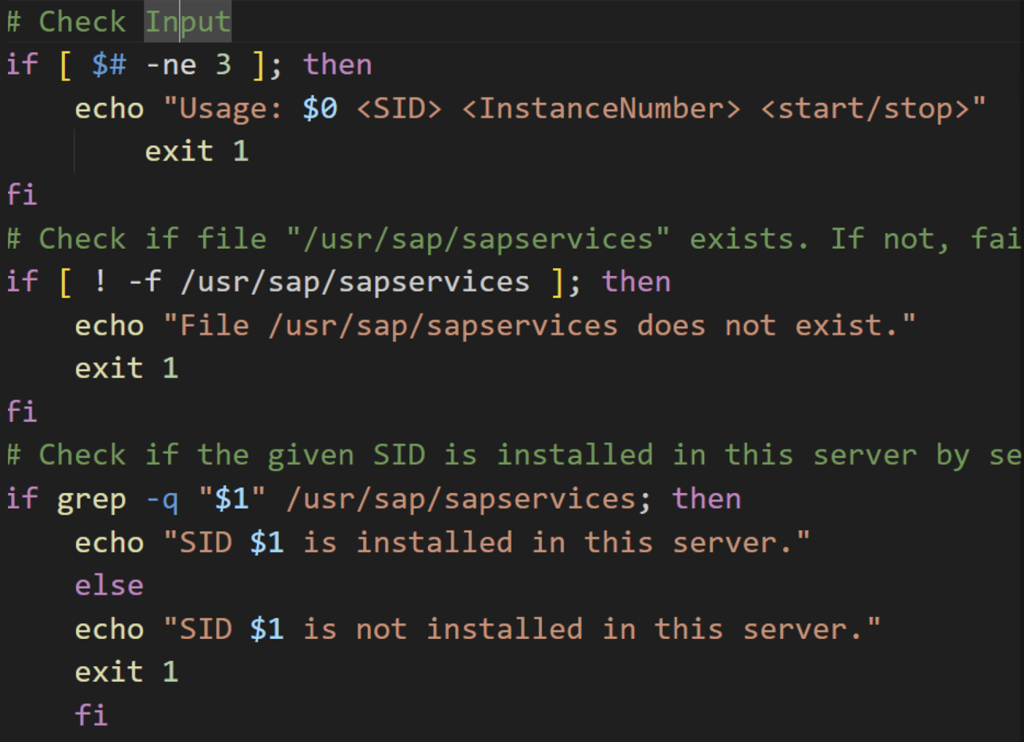
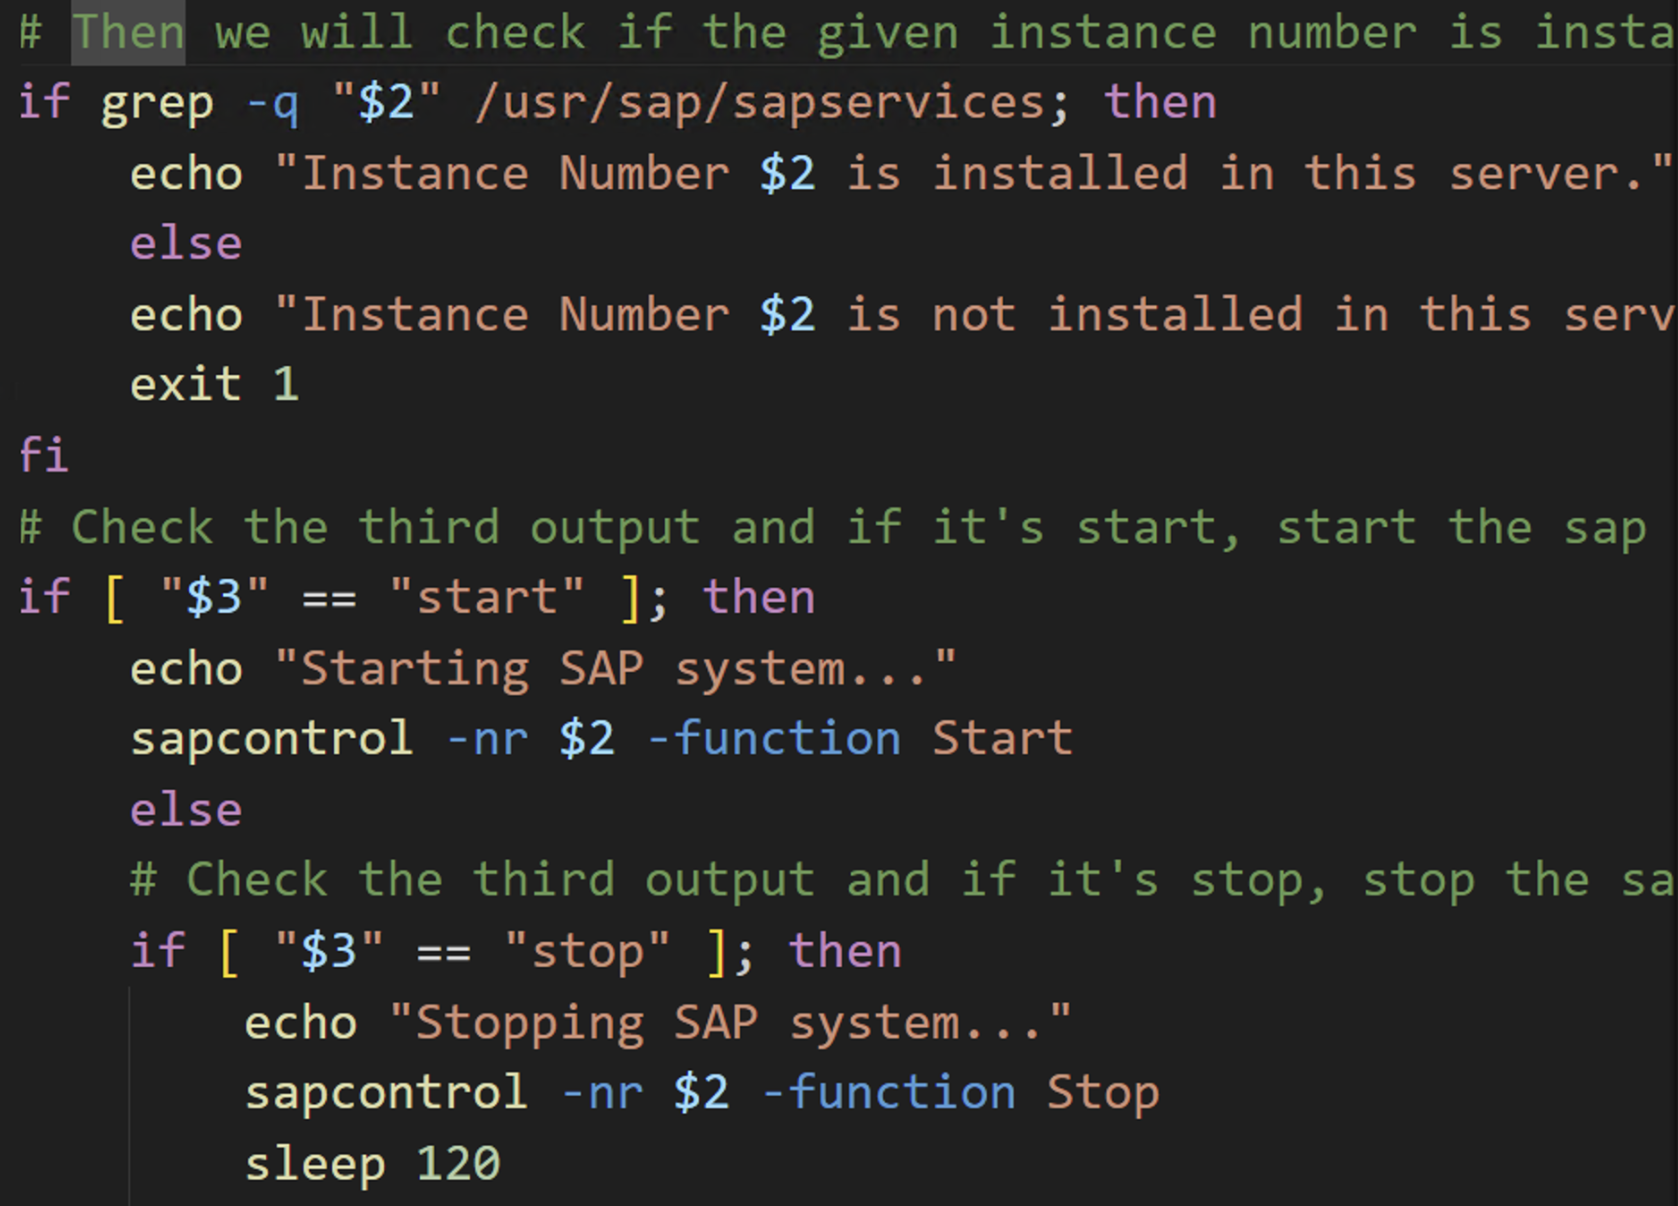
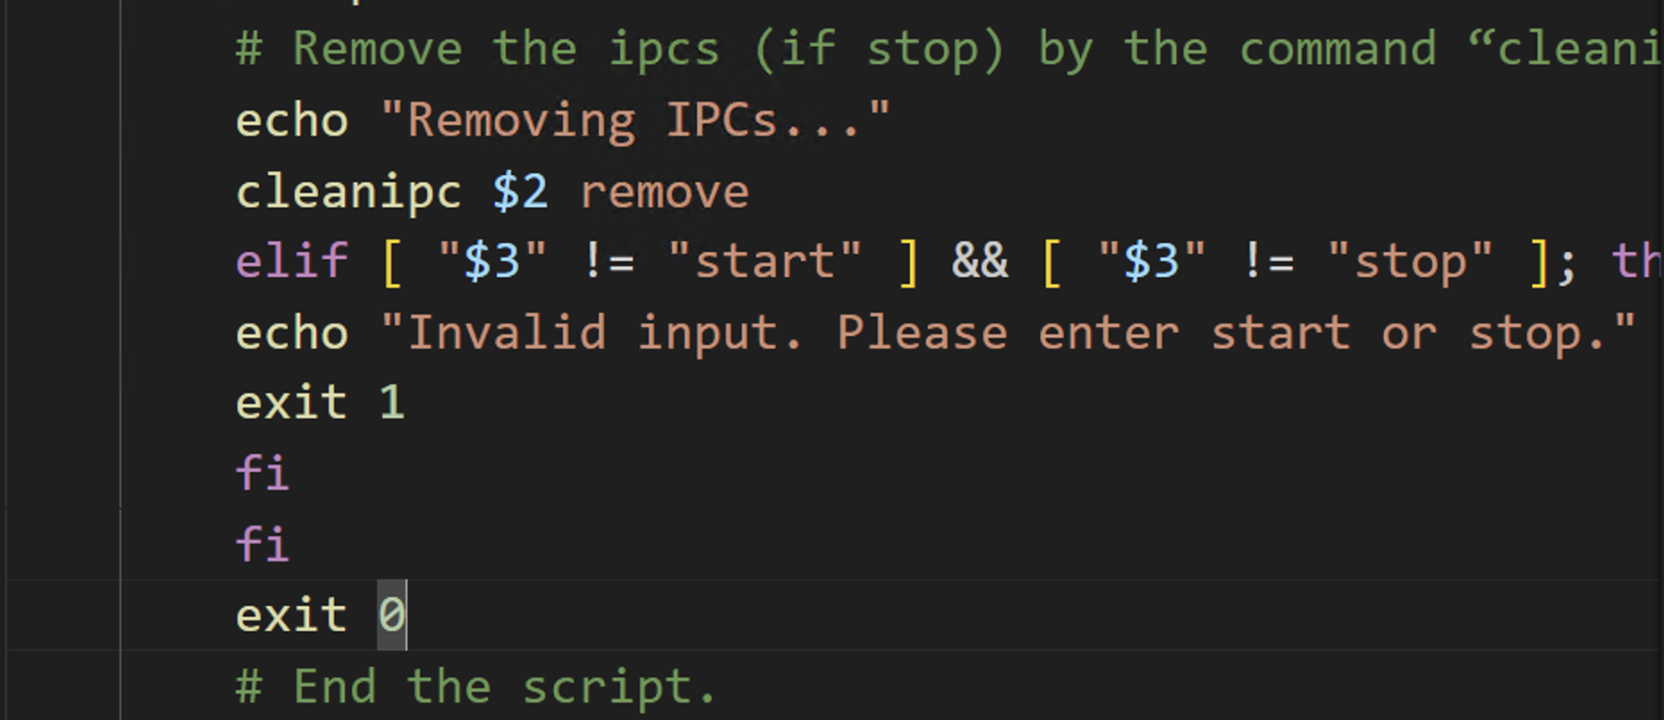
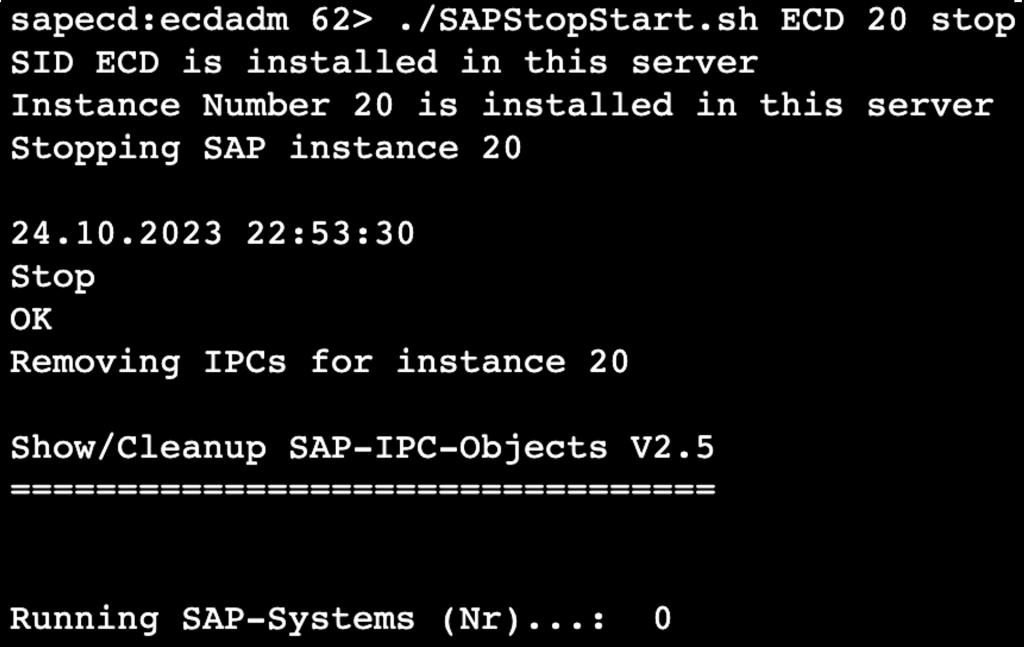


 Sharmila Shanmugam is a Solutions Architect at Amazon Web Services. She is passionate about solving the customers’ business challenges with technology and automation and reduce the operational overhead. In her current role, she helps customers across industries in their digital transformation journey and build secure, scalable, performant and optimized workloads on AWS.
 Harsh Bansal is an Analytics Solutions Architect with Amazon Web Services. In his role, he collaborates closely with clients, assisting in their migration to cloud platforms and optimizing cluster setups to enhance performance and reduce costs. Before joining AWS, he supported clients in leveraging OpenSearch and Elasticsearch for diverse search and log analytics requirements.
 Rohit Kumar works as a Cloud Support Engineer in the Support Engineering team at Amazon Web Services. He focuses on Amazon OpenSearch Service, offering guidance and technical help to customers, helping them create scalable, highly available, and secure solutions on AWS Cloud. Outside of work, Rohit enjoys watching or playing cricket. He also loves traveling and discovering new places. Essentially, his routine revolves around eating, traveling, cricket, and repeating the cycle.


 Sudipta Mitra is a Senior Data Architect for AWS, and passionate about helping customers to build modern data analytics applications by making innovative use of latest AWS services and their constantly evolving features. A pragmatic architect who works backwards from customer needs, making them comfortable with the proposed solution, helping achieve tangible business outcomes. His main areas of work are Data Mesh, Data Lake, Knowledge Graph, Data Security and Data Governance.
 Deepak Sharma is a Senior Data Architect with the AWS Professional Services team, specializing in big data and analytics solutions. With extensive experience in designing and implementing scalable data architectures, he collaborates closely with enterprise customers to build robust data lakes and advanced analytical applications on the AWS platform.
 Nanda Chinnappa is a Cloud Infrastructure Architect with AWS Professional Services at Amazon Web Services. Nanda specializes in Infrastructure Automation, Cloud Migration, Disaster Recovery and Databases which includes Amazon RDS and Amazon Aurora. He helps AWS Customer’s adopt AWS Cloud and realize their business outcome by executing cloud computing initiatives.


 Figure 8 – connectivity troubleshooting response generated by Amazon Q


 ” width=”1252″ height=”889″>
 ” width=”1280″ height=”720″>
 ” width=”863″ height=”521″>
 ” width=”865″ height=”582″>
 ” width=”1497″ height=”1173″>
 ” width=”1336″ height=”1313″>
 ” width=”1333″ height=”1364″>


 Nihar Sheth is a Senior Product Manager at Amazon Web Services. He is passionate about developing intuitive product experiences that solve complex customer problems and enable customers to achieve their business goals.


 Anand Komandooru is a Principal Cloud Architect at AWS. He joined AWS Professional Services organization in 2021 and helps customers build cloud-native applications on AWS cloud. He has over 20 years of experience building software and his favorite Amazon leadership principle is “
 Rama Krishna Ramaseshu is a Senior Application Architect at AWS. He joined AWS Professional Services in 2022 and with close to two decades of experience in application development and software architecture, he empowers customers to build well architected solutions within the AWS cloud. His favorite Amazon leadership principle is “
 Sachin Vighe is a Senior DevOps Architect at AWS. He joined AWS Professional Services in 2020, and specializes in designing and architecting solutions within the AWS cloud to guide customers through their DevOps and Cloud transformation journey. His favorite leadership principle is “
 Molly Wu is an Associate Cloud Developer at AWS. She joined AWS Professional Services in 2023 and specializes in assisting customers in building frontend technologies in AWS cloud. Her favorite leadership principle is “
 Andrew Yankowsky is a Security Consultant at AWS. He joined AWS Professional Services in 2023, and helps customers build cloud security capabilities and follow security best practices on AWS. His favorite leadership principle is “



 Shoukat Ghouse is a Senior Big Data Specialist Solutions Architect at AWS. He helps customers around the world build robust, efficient and scalable data platforms on AWS leveraging AWS analytics services like AWS Glue, AWS Lake Formation, Amazon Athena and Amazon EMR.


 Kinnar Kumar Sen is a Sr. Solutions Architect at Amazon Web Services (AWS) focusing on Flexible Compute. As a part of the EC2 Flexible Compute team, he works with customers to guide them to the most elastic and efficient compute options that are suitable for their workload running on AWS. Kinnar has more than 15 years of industry experience working in research, consultancy, engineering, and architecture.
 Alex Lines is a Principal Containers Specialist at AWS helping customers modernize their Data and ML applications on Amazon EKS.
 Mengfei Wang is a Software Development Engineer specializing in building large-scale, robust software infrastructure to support big data demands on containers and Kubernetes within the EMR on EKS team. Beyond work, Mengfei is an enthusiastic snowboarder and a passionate home cook.
 Jerry Zhang is a Software Development Manager in AWS EMR on EKS. His team focuses on helping AWS customers to solve their business problems using cutting-edge data analytics technology on AWS infrastructure.
Response:
3) Send test message
Response:
Response – (ConflictException):
Conclusion
As SMS messaging continues to play a crucial role in customer engagement and authentication, protecting your communications from AIT is more important than ever. Amazon Pinpoint Protect provides a powerful and user-friendly solution to help you mitigate the impact of SMS pumping, ensuring the integrity of your SMS channels and preserving your business’ reputation and resources. Whether you’re a small business or a large enterprise, Pinpoint Protect is a valuable tool to have in your arsenal as you navigate the evolving landscape of SMS messaging.
To get started with Pinpoint SMS Protect, visit the Amazon Pinpoint SMS documentation or reach out to your AWS account team. And don’t forget to let us know in the comments how Protect configurations has helped you combat AIT and strengthen your SMS communications.
A few resources to help you plan for your SMS program:
About the Author
Brett Ezell is your friendly neighborhood Solutions Architect at AWS, where he specializes in helping customers optimize their SMS and email campaigns using Amazon Pinpoint and Amazon Simple Email Service. As a former US Navy veteran, Brett brings a unique perspective to his work, ensuring customers receive tailored solutions to meet their needs. In his free time, Brett enjoys live music, collecting vinyl, and the challenges of a good workout. And, as a self-proclaimed comic book aficionado, he can often be found combing through his local shop for new books to add to his collection.