Tag Archives: Amazon Sagemaker

Cross-account lakehouse governance with Amazon S3 Tables and SageMaker Catalog

Post Syndicated from Sneha Rao original https://aws.amazon.com/blogs/big-data/cross-account-lakehouse-governance-with-amazon-s3-tables-and-sagemaker-catalog/

Organizations increasingly face challenges when analyzing data stored across multiple AWS accounts and storage formats. Data teams often need to query both traditional Amazon Simple Storage Service (Amazon S3) objects and Apache Iceberg tables, leading to costly data duplication, potential inconsistencies, and complex permission management across accounts.

To address these challenges, you can combine Amazon S3 Tables, which provides native Apache Iceberg support within S3, with Amazon SageMaker Catalog for unified data governance. This solution supports secure cross-account data access without duplicating datasets or compromising security controls.

In this post, we walk you through a practical solution for secure, efficient cross-account data sharing and analysis. You’ll learn how to set up cross-account access to S3 Tables using federated catalogs in Amazon SageMaker, perform unified queries across accounts with Amazon Athena in Amazon SageMaker Unified Studio, and implement fine-grained access controls at the column level using AWS Lake Formation.

This post helps you establish proper governance and security controls for S3 Tables in a multi-account environment, enabling secure and efficient cross-account data access.

Solution overview

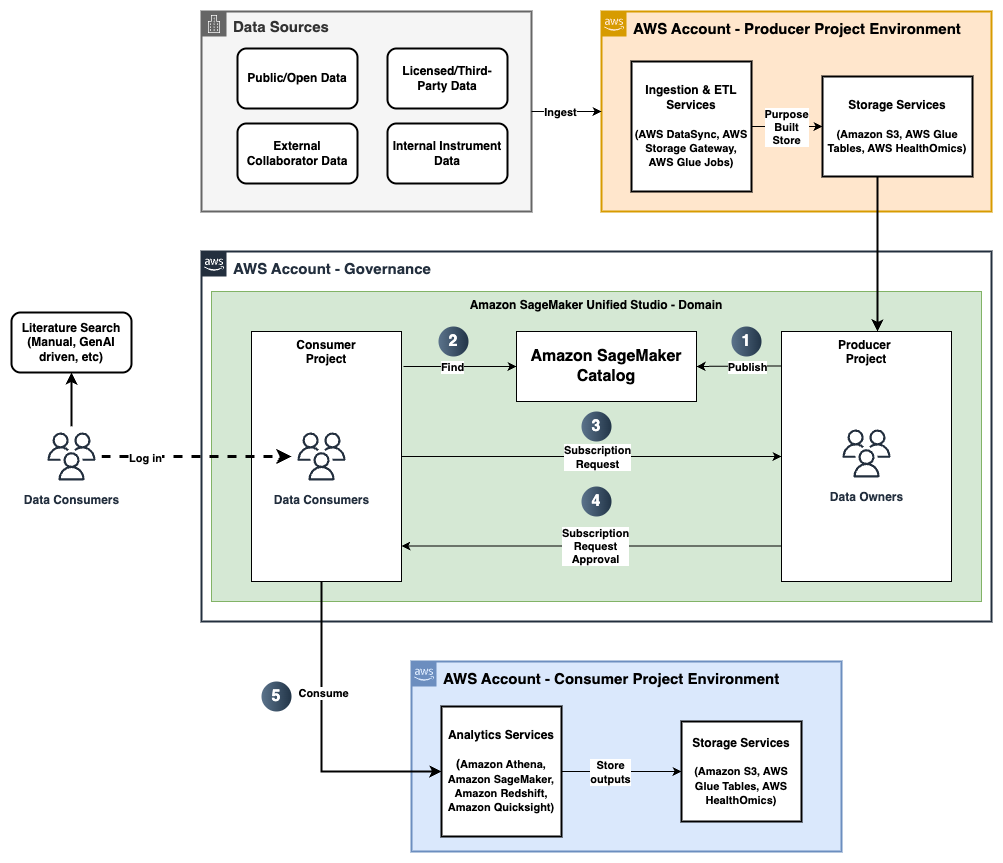
We walk you through implementing a three-account lakehouse governance architecture where you can securely share data. As shown in the following diagram, Account A serves as your data producer with S3 Tables, Account B acts as your central governance hub with SageMaker Catalog, and Account C represents your data consumers. We’ll demonstrate step-by-step how to configure cross-account access and implement governance controls so consumers can discover and query data from both S3 tables and traditional S3 buckets.

Prerequisite and Set up

In this post, we focus on how to do the cross account set up and how to onboard S3 Tables. All three accounts are in the same AWS Region. To implement this solution, you will need three individual accounts (A, B, C). The setup in the accounts should look like the following:

  • Account A (Producer): Create an Amazon S3 Table on the account.
  • Account B (Central governance and producer): This is another account where you have data in Amazon S3 buckets catalog via Glue Catalog. You would onboard these into domain portal.
  • Account C (Consumer account): Identify an account where you have consumers query data using Athena to follow along.

The following are the high-level implementation steps for this solution:

Step 1: Configure cross-account association for governance.
Step 2: Create three Project Profiles in Account B pointing to tables in Account A, B, and C.
Step 3: Create three Projects.
Step 4: Set up permissions for Projects in AWS Lake Formation.
Step 5: In Account B, create Datasource to connect S3 Table from Account A and Glue Catalog Tables from Account B.
Step 6: Publish and Subscribe to asset.
Step 7: Query S3 table (Account A) and S3 (Account B) data together in SQL editor (Account C).

Step 1

A. Configure cross-account association for governance

In this section, we associate Account A and C in the Governance account B.

  1. Open the SageMaker Unified Studio console in Account B.
  2. Navigate to Domains, select your domain, then choose the Account associations tab.
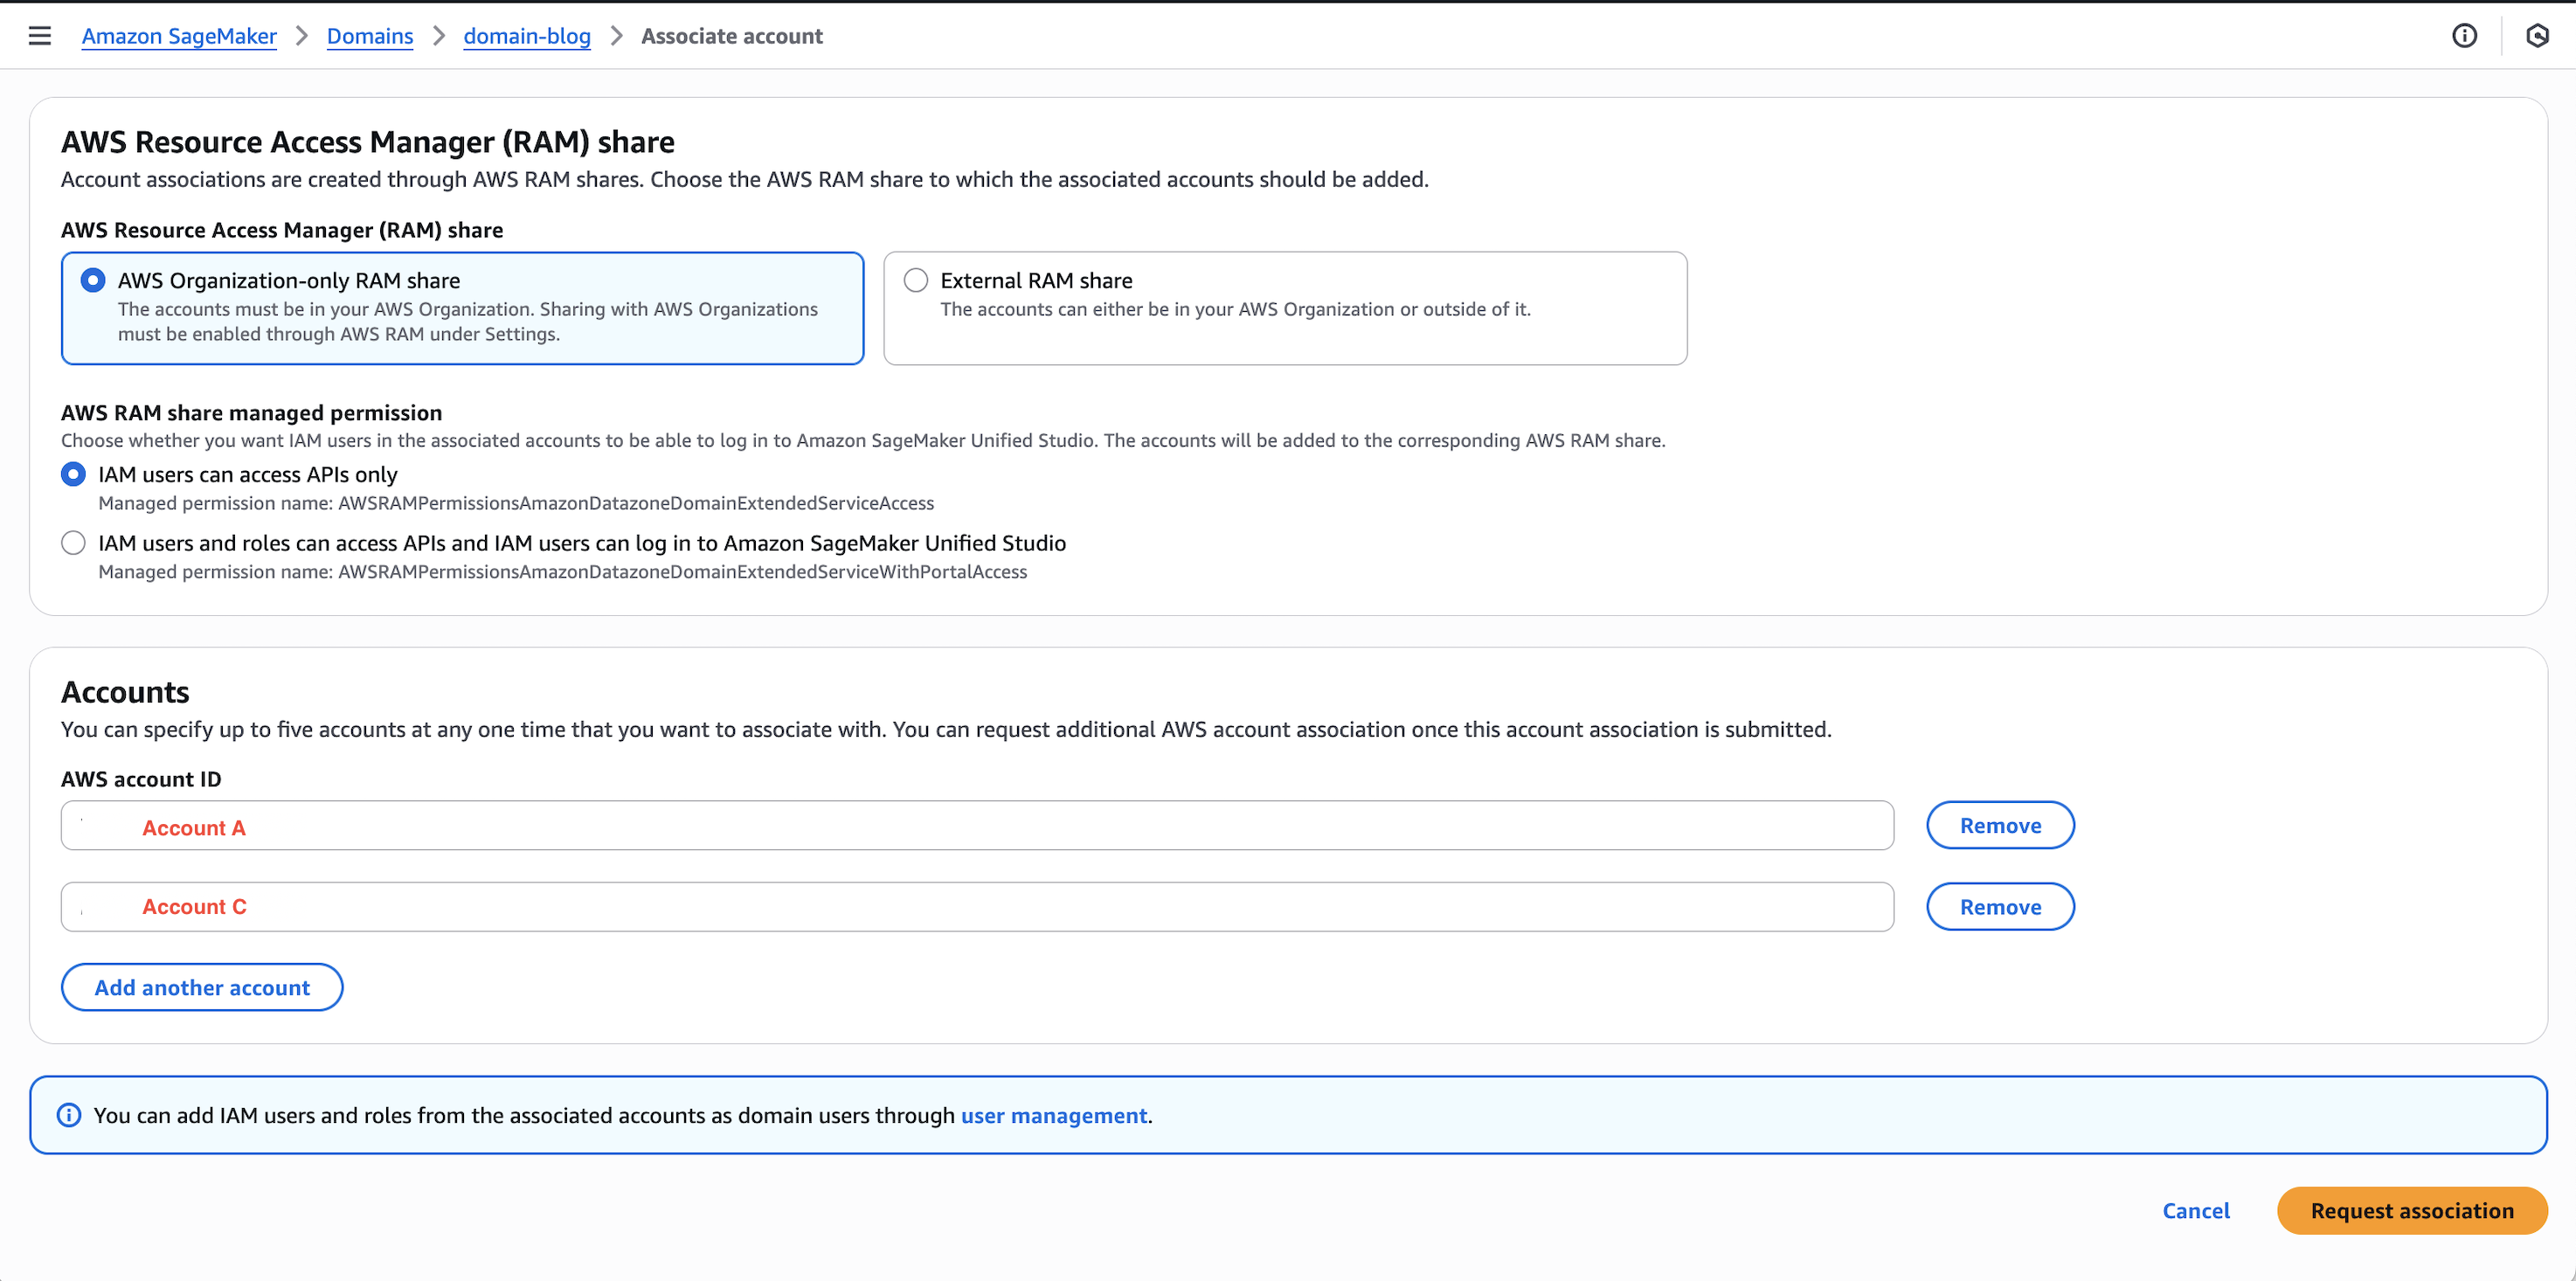
  3. Choose Request association and enter the Account IDs for Account A and Account C.
  4. Submit the association request and verify the accounts appear with “Requested” status.

B. Enable Blueprints for your domain in Accounts A, B, and C

The LakeHouseDatabase blueprint enables SageMaker Unified Studio to securely manage, query, and share data from S3, Redshift, and other sources using open standards—so in this step, you enable it in Accounts A, B, and C to support unified data access and collaboration.

  1. In Account A, in the SageMaker console, navigate to your domain and select the Blueprints tab.
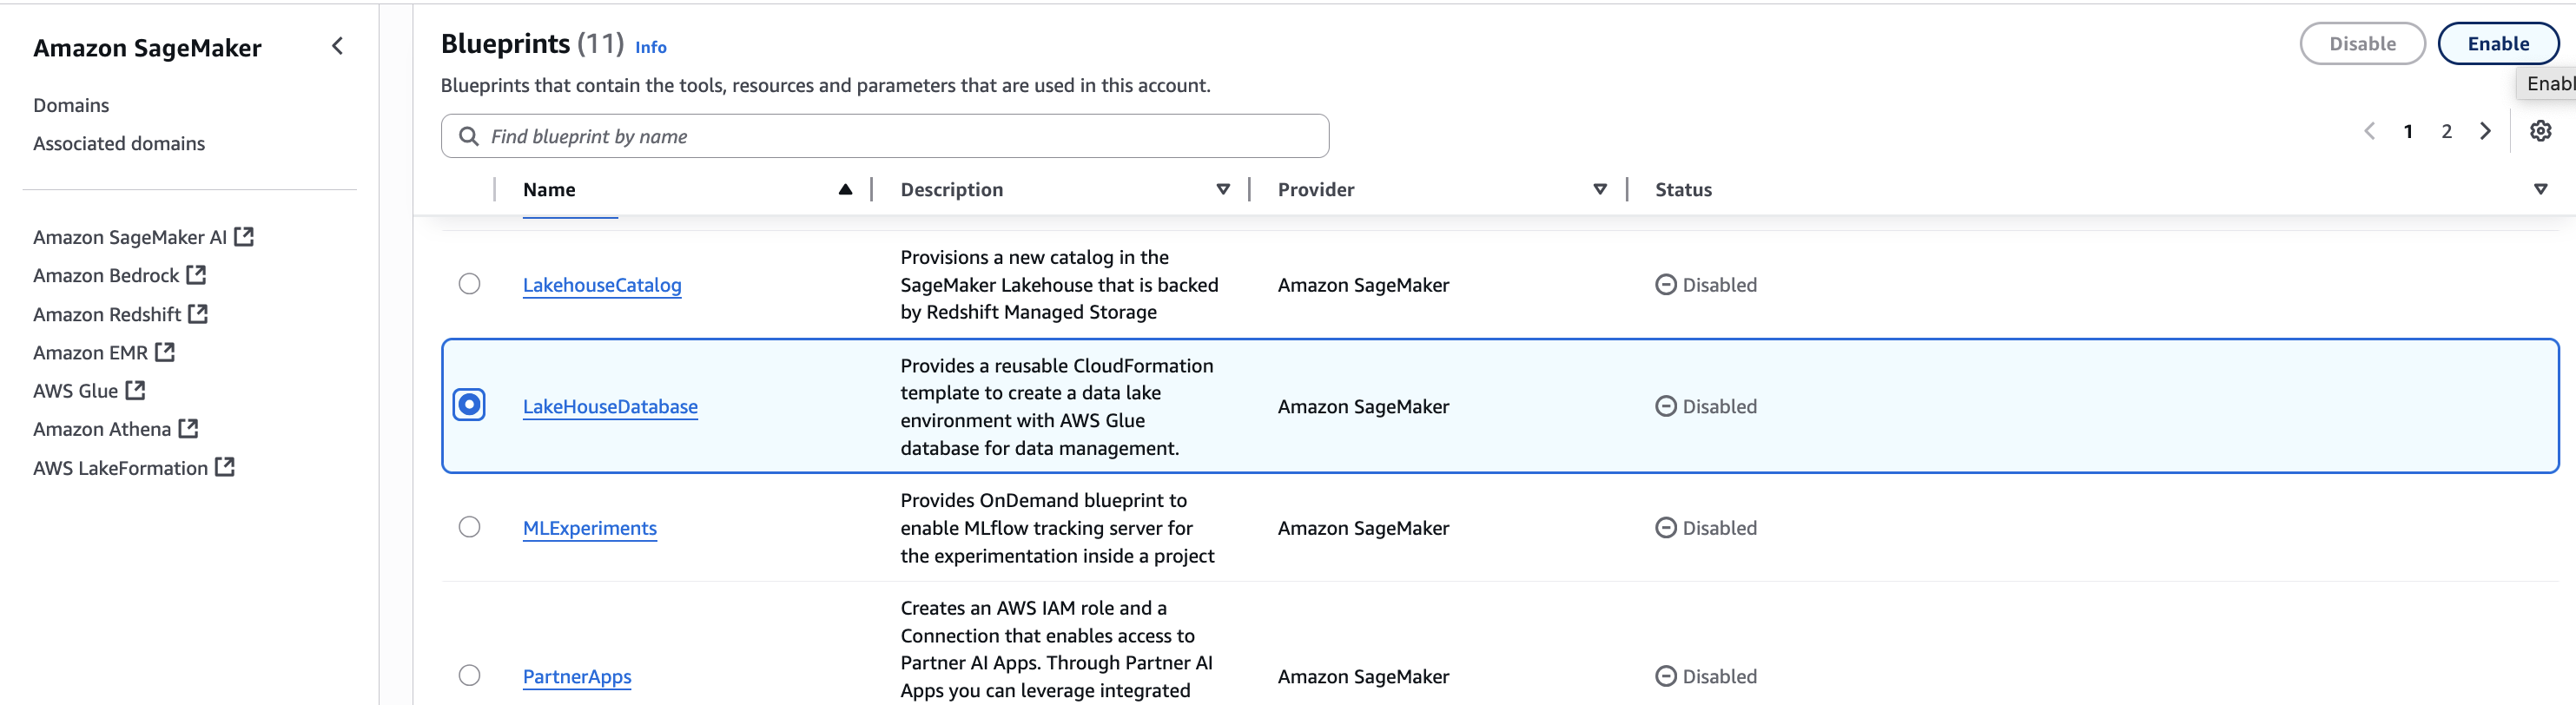
  2. Select the LakeHouseDatabase blueprint and choose Enable.
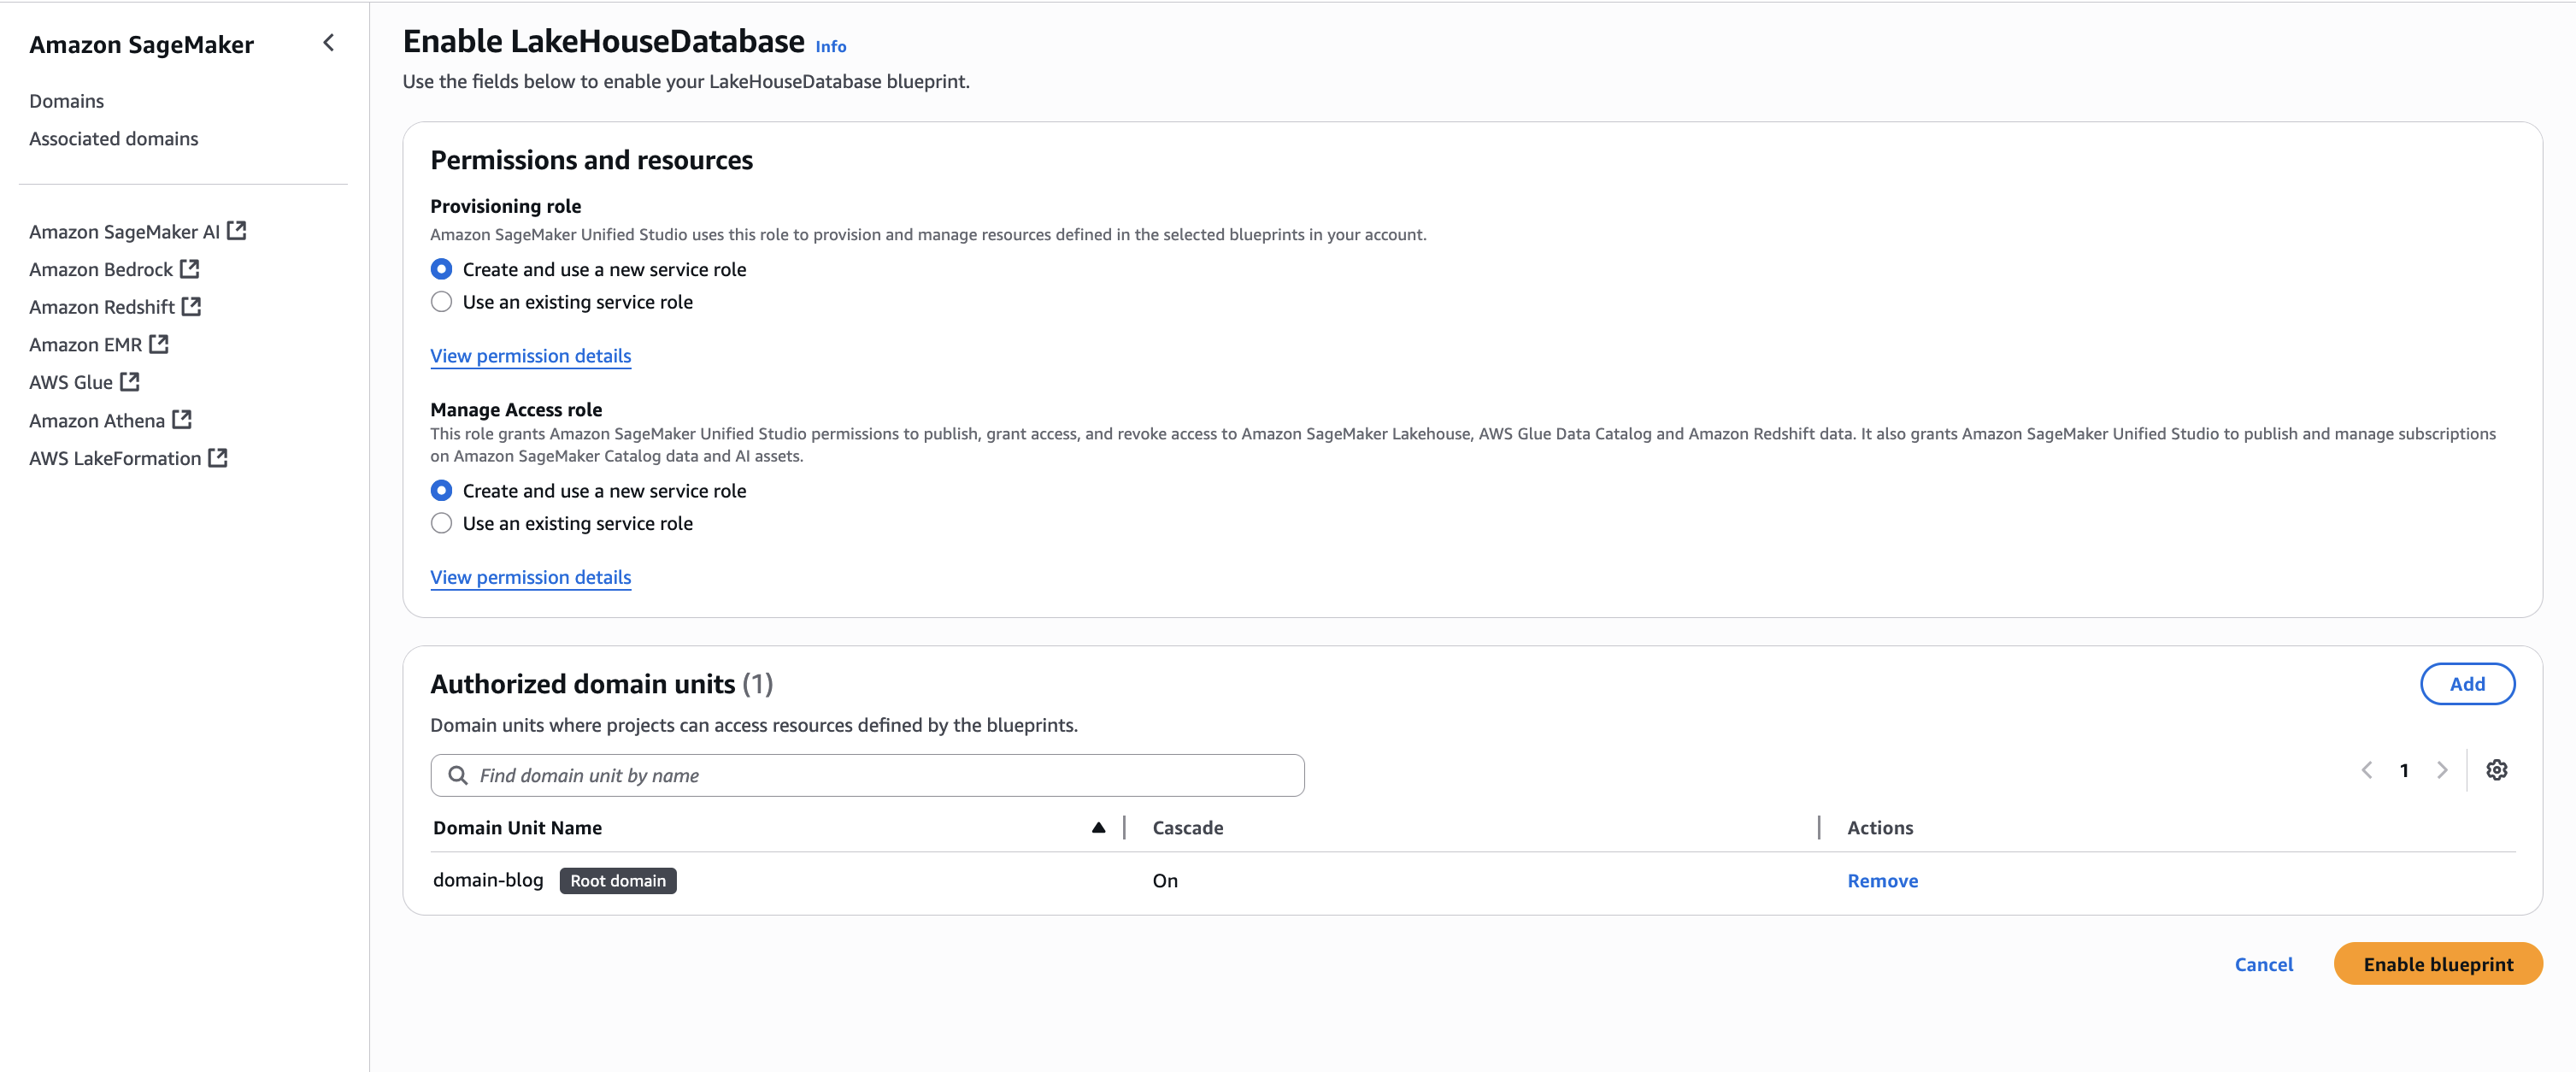
  3. Keeping the Permissions and resources section at the default settings, choose Enable Blueprint.
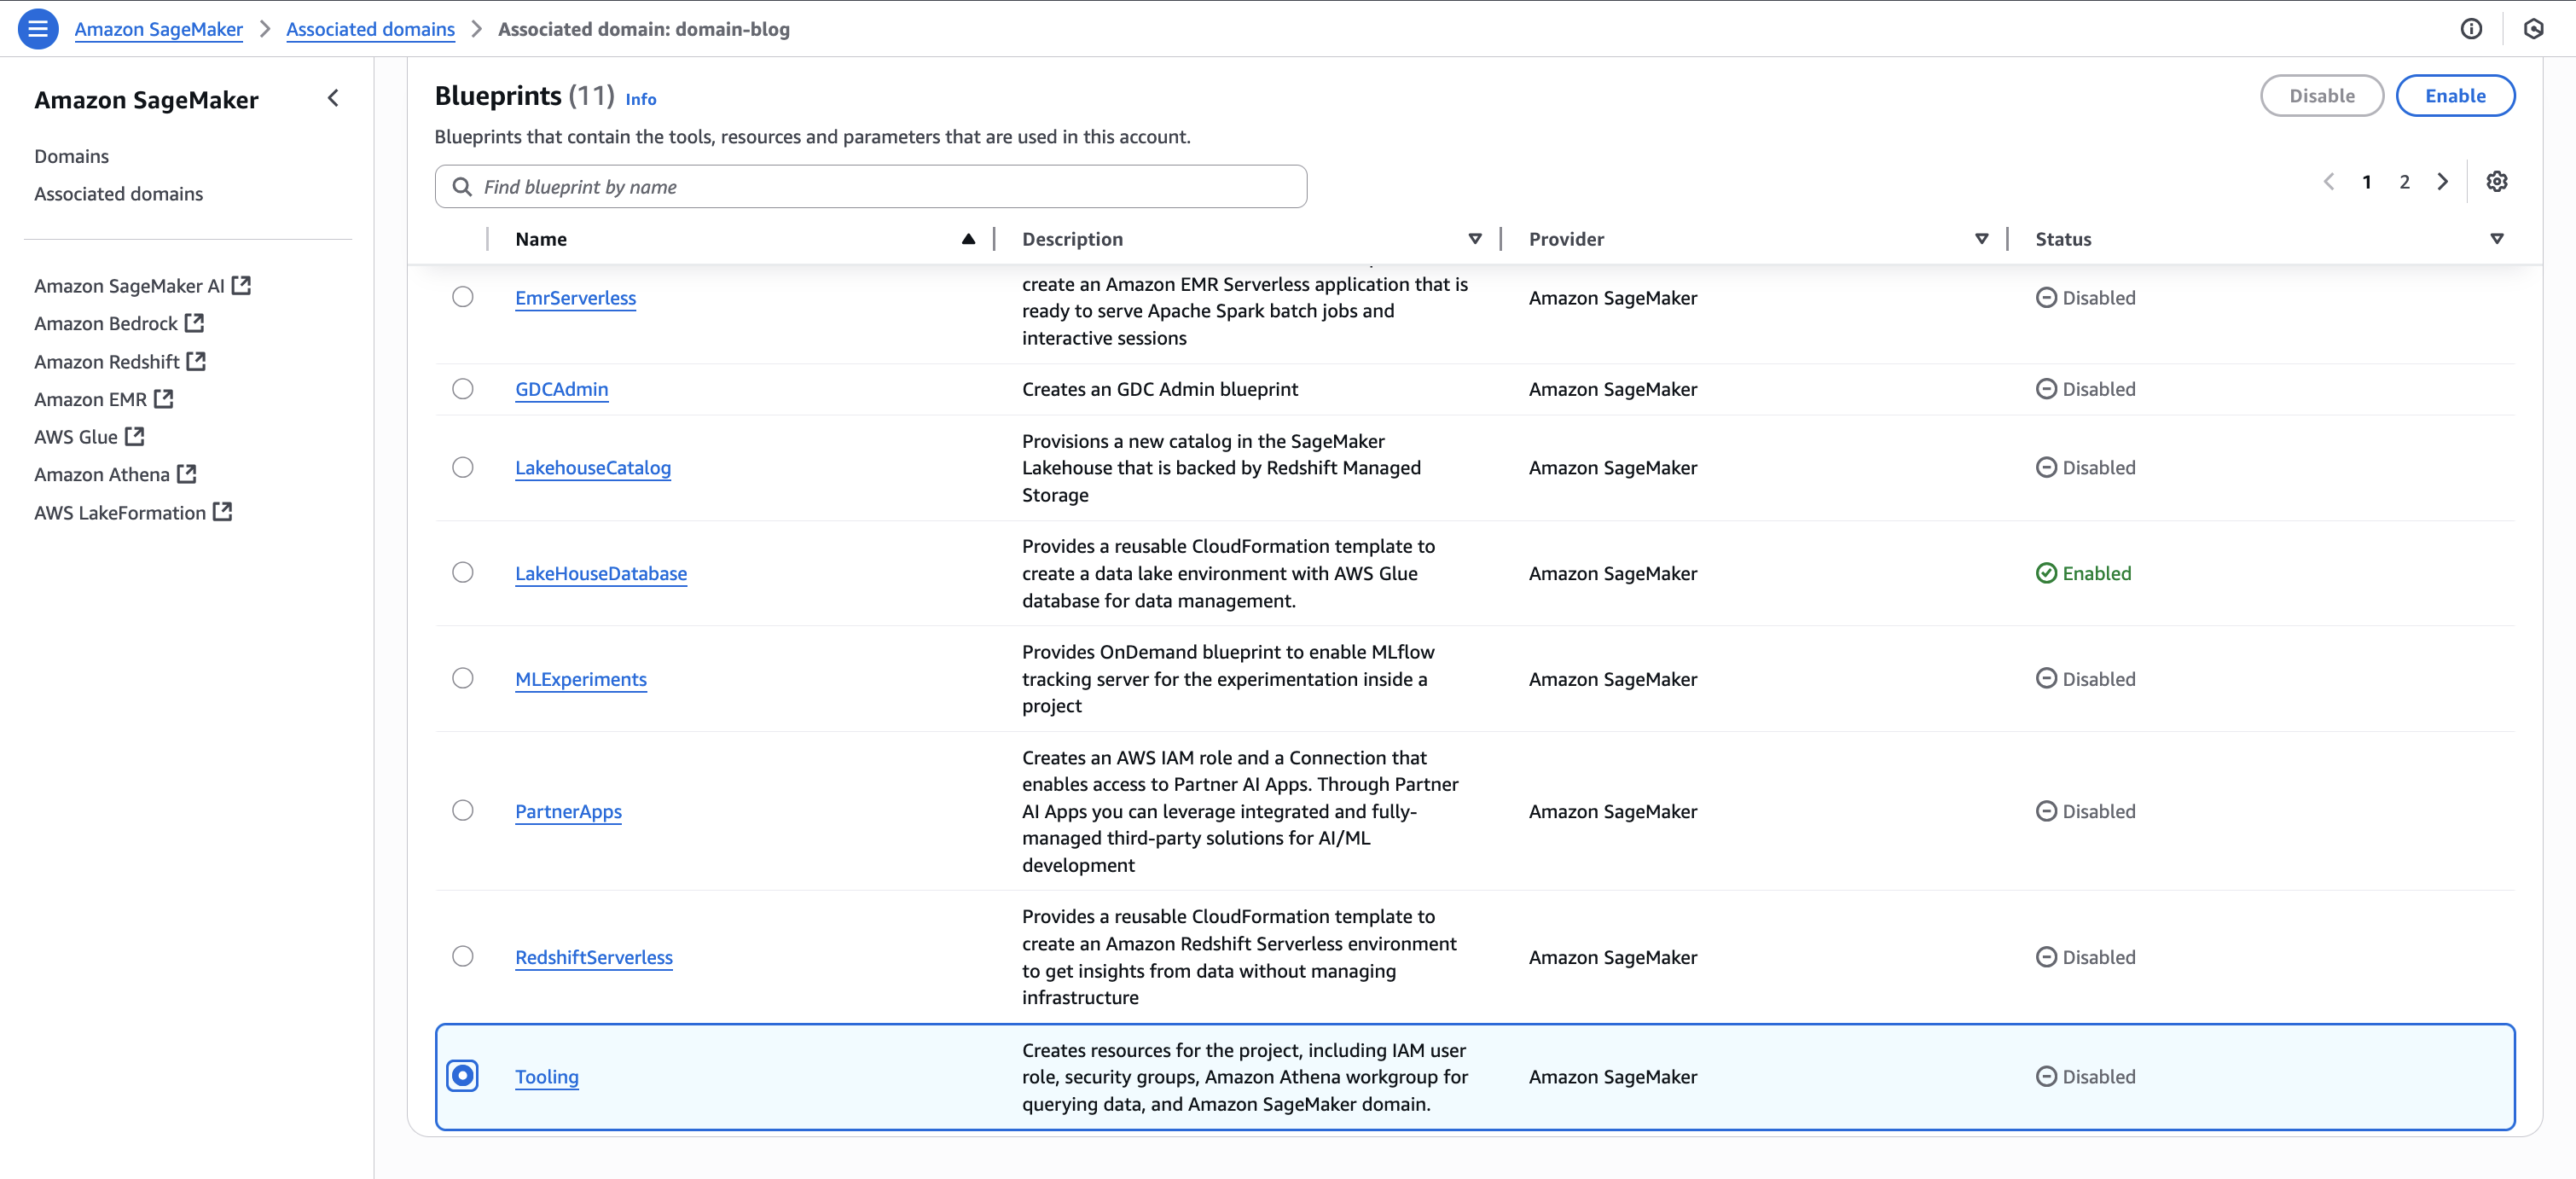
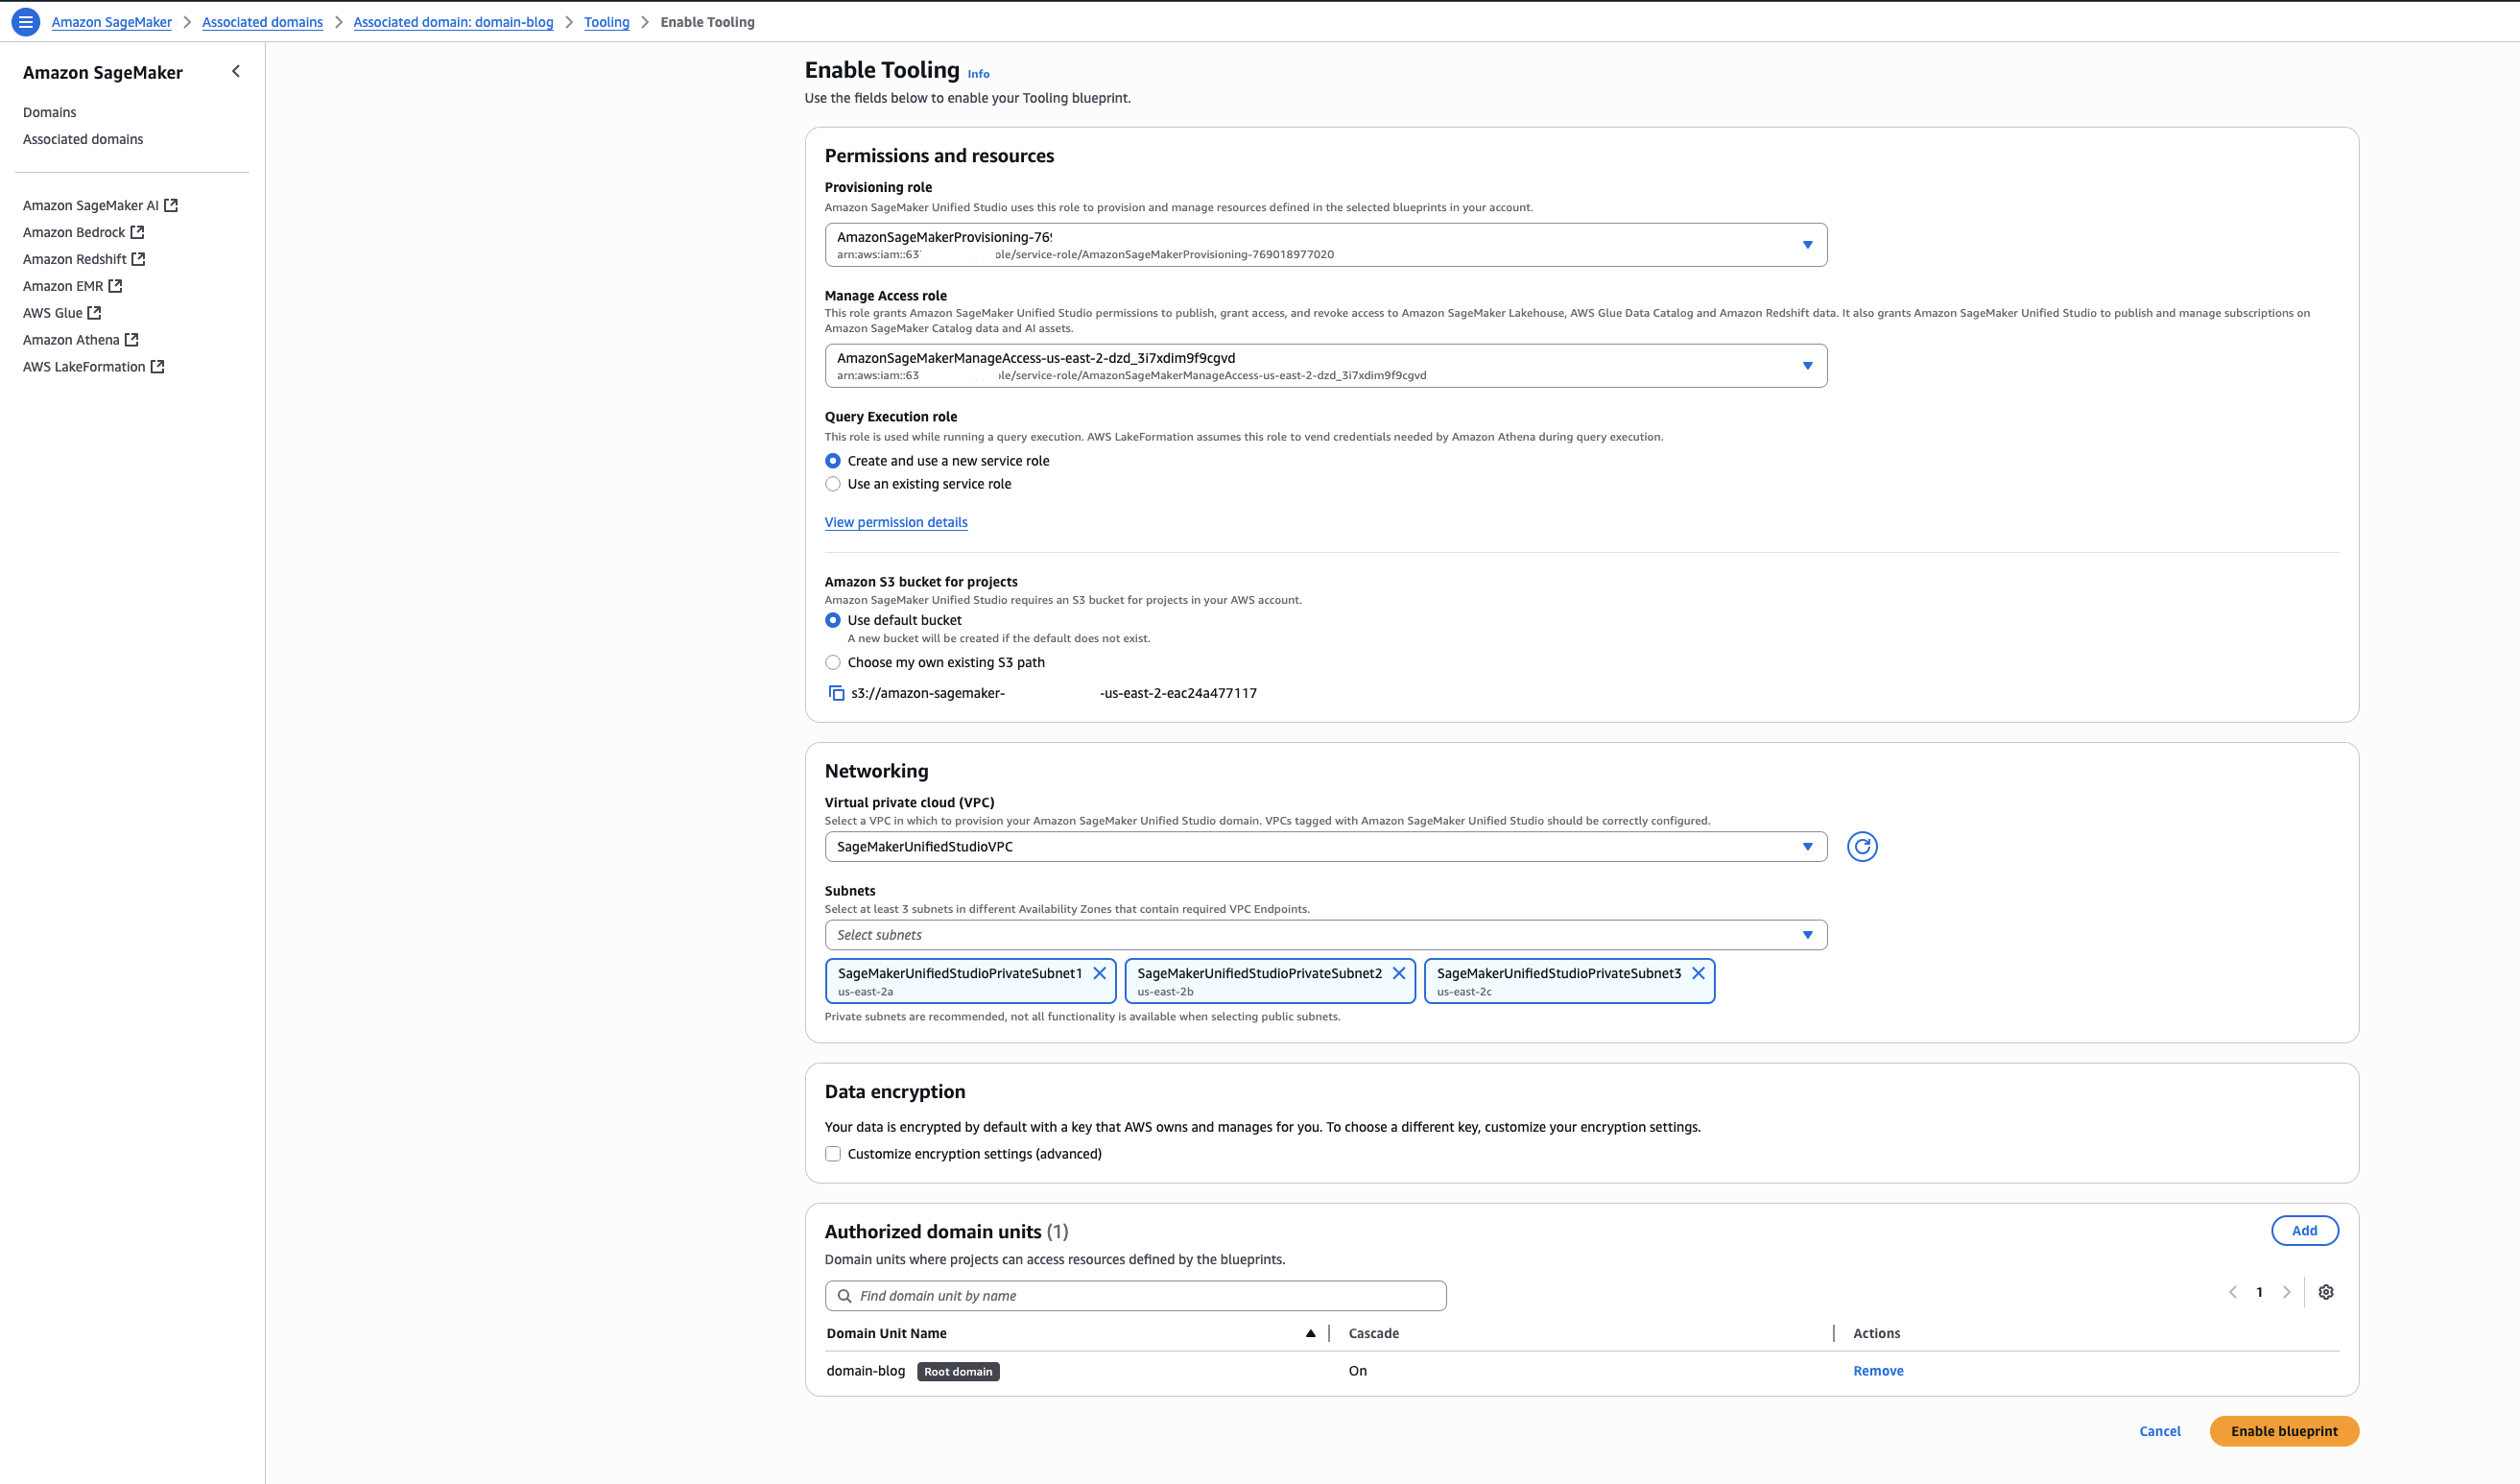
  4. Back on the blueprints screen, select the Tooling blueprint and choose Enable.
  5. Keeping the Permissions and resources section at the default settings, configure the Networking section with the desired VPC and subnet configurations.
  6. Choose Enable Blueprint.
  7. Repeat Step1.B and enable the same blueprints in Account B to make S3 data publishable and Account C so consumers can query the data using Athena.

Step 2: Create Project Profiles in Account B

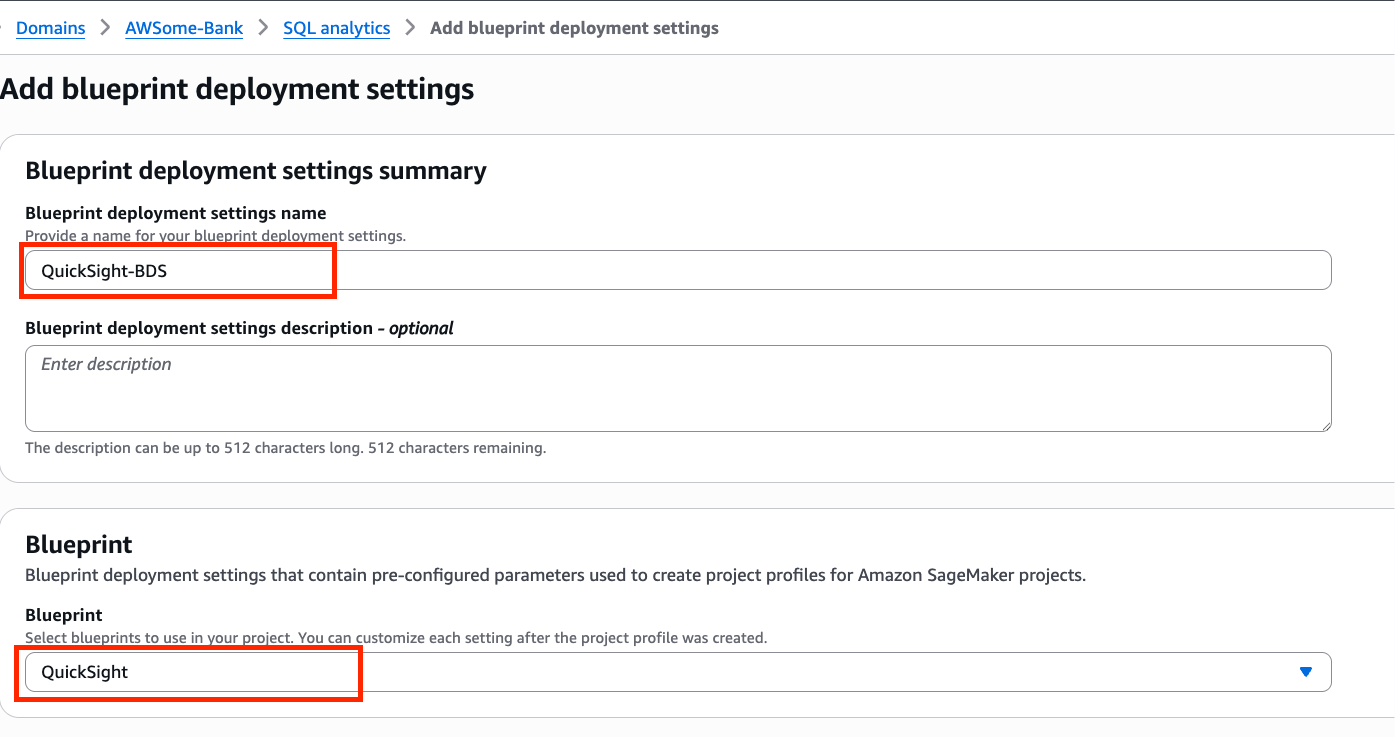
Use the documentation to create three project profiles in Account B using the ‘LakeHouseDatabase’ Blueprint, with each profile configured for Accounts A, B, and C respectively. For this post, we use the following naming convention:

  • datalake-project-profile-s3tables (for Account A)
  • datalake-project-profile (for Account B)
  • datalake-project-profile-consumer (for Account C)

Step 3: Create three Projects for accounts A, B, and C

  1. Using the documentation, create one Project in each account. For this post, we use the following naming convention:
    • ‘producer-s3tables’ – This is configured for Account A
    • ‘producer-s3’ – This is configured for Account B
    • ‘consumer’ – This is configured for Account C
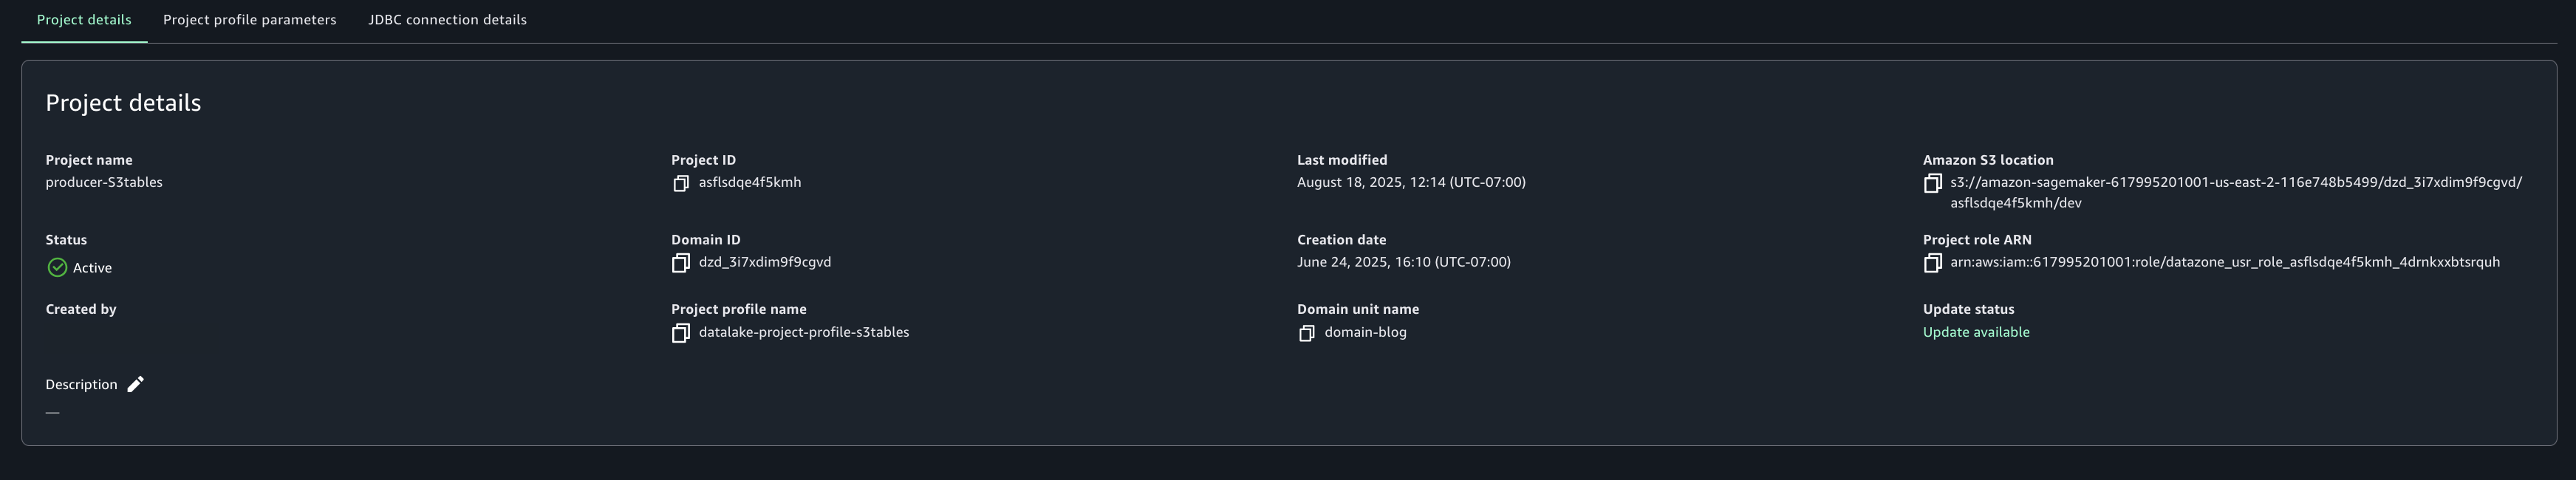
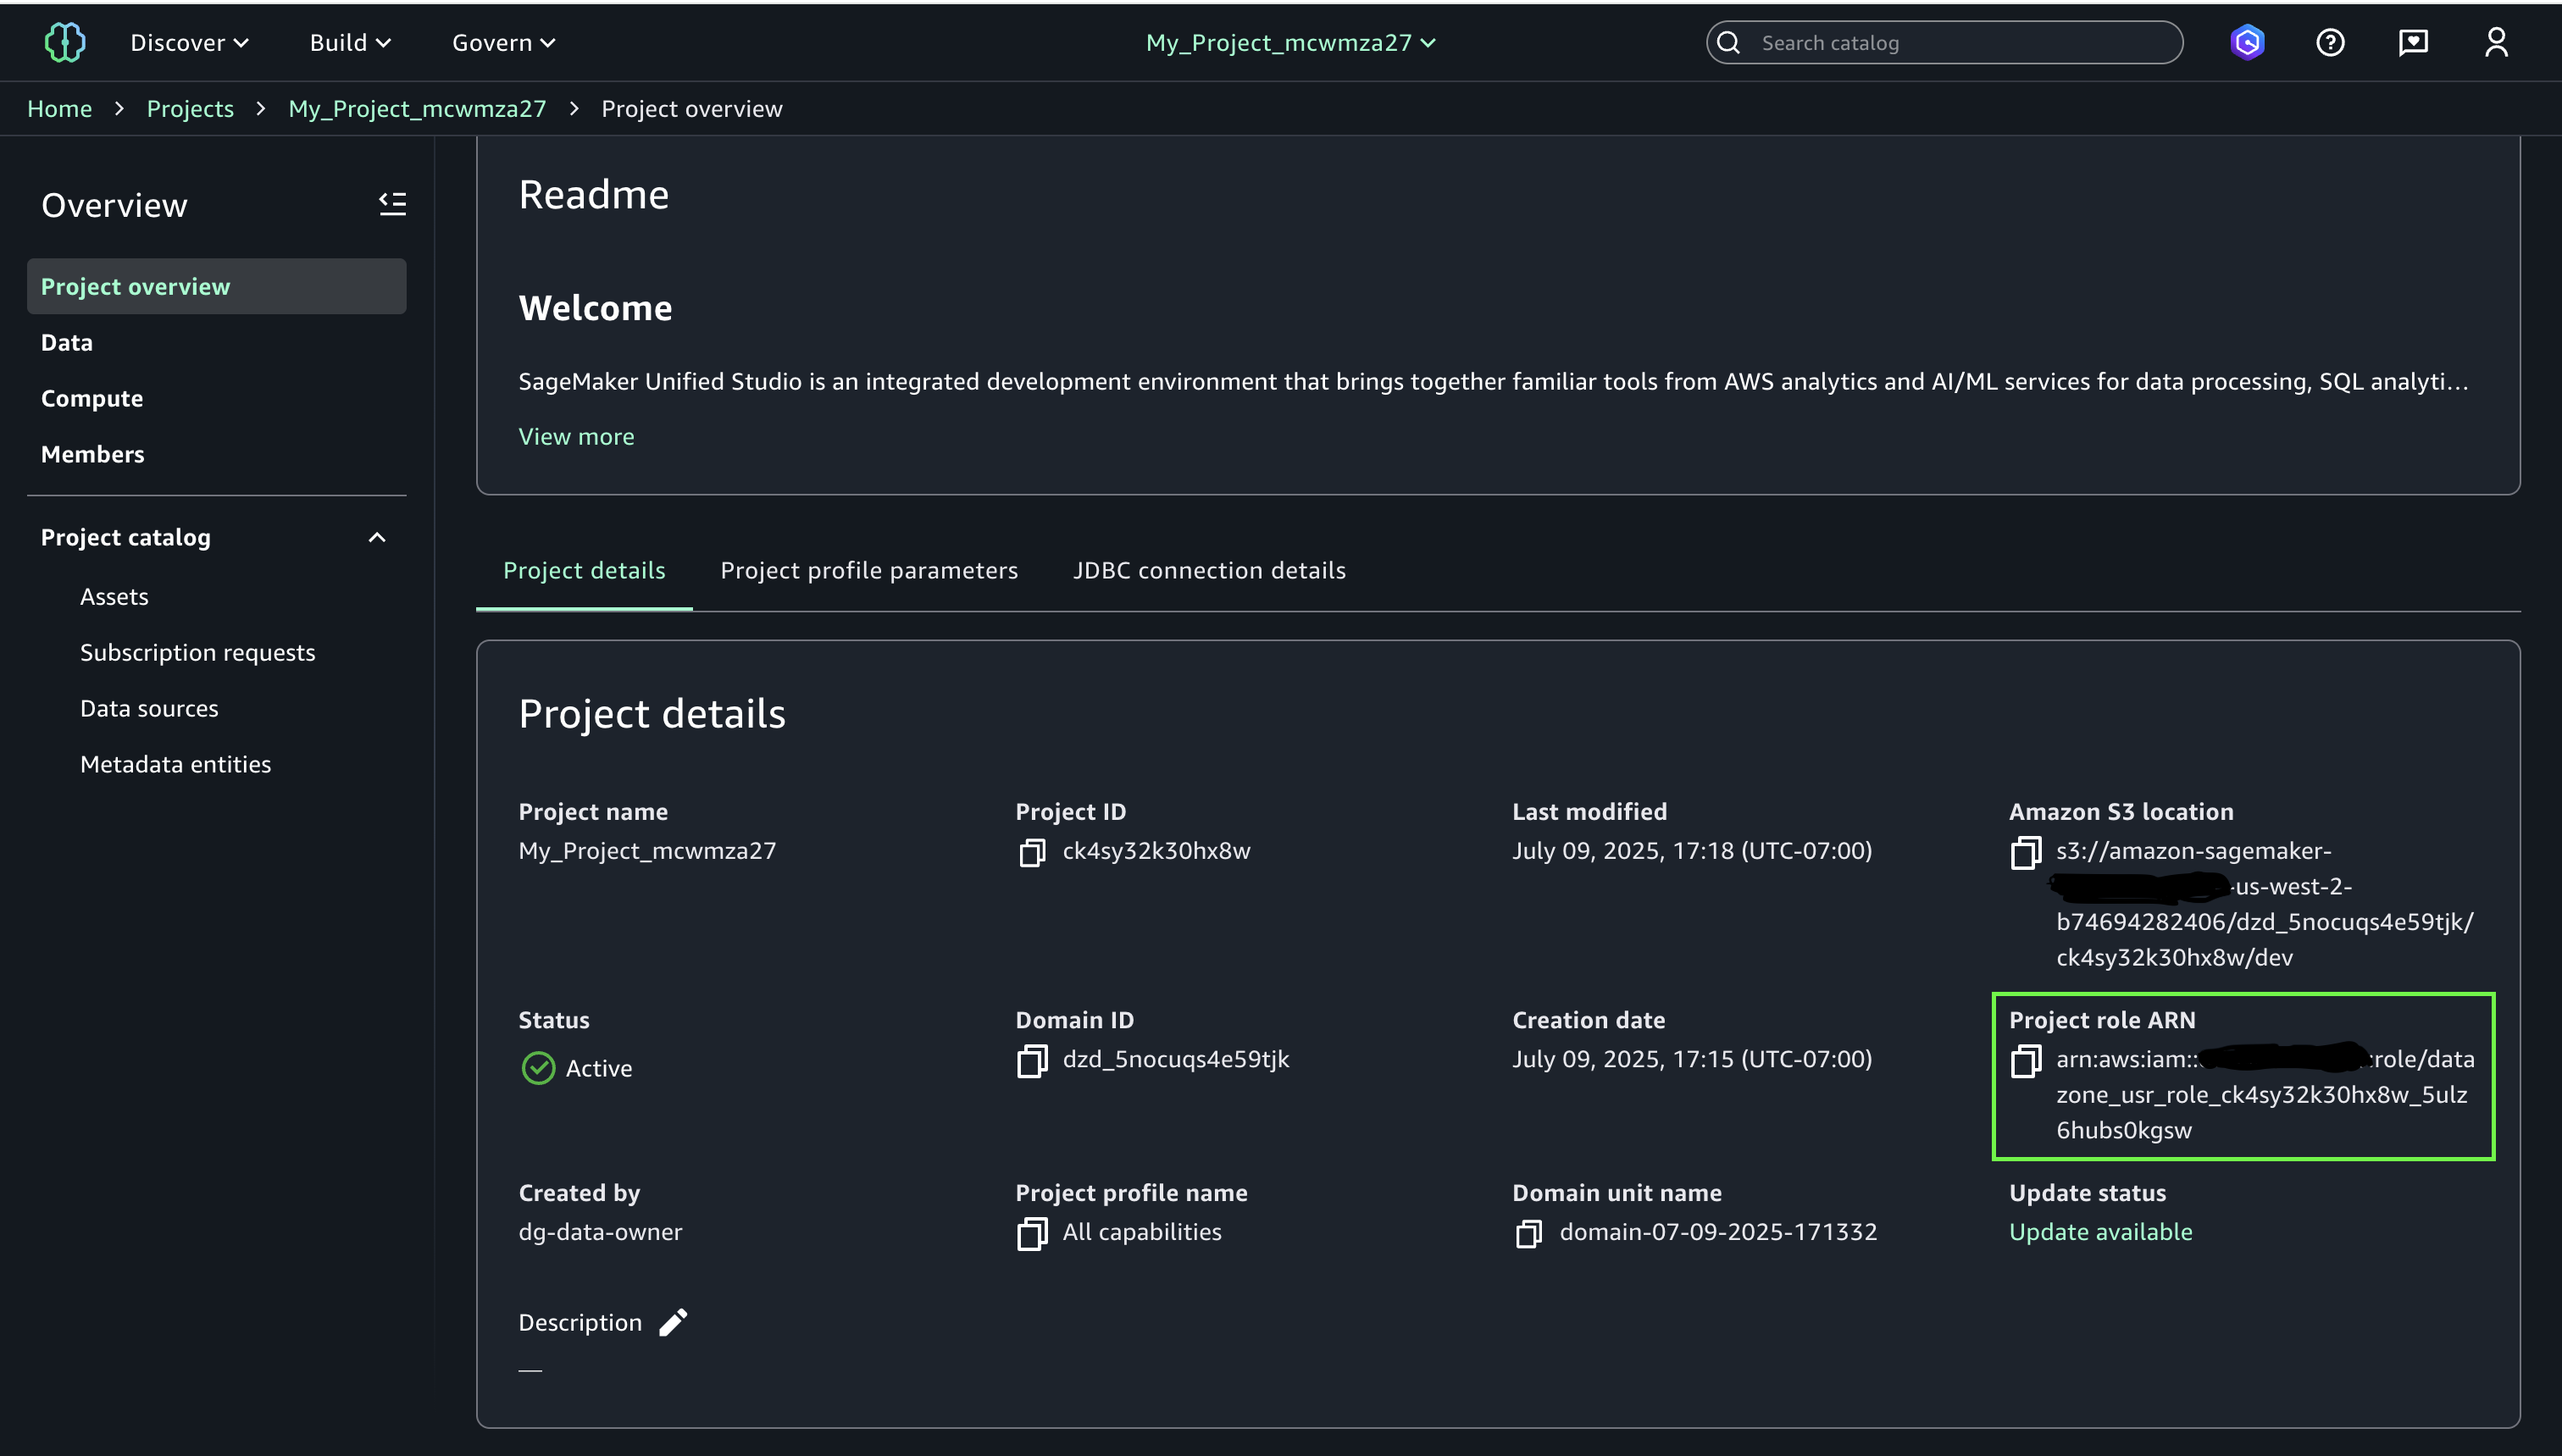
  2. After creating the Project, locate and make note of the Project role ARN listed under Project details on the project overview page.

Step 4: Set up permissions for Projects in AWS Lake Formation

In Account A, onboard the S3 table in SageMaker Lakehouse and grant permissions to the project role:

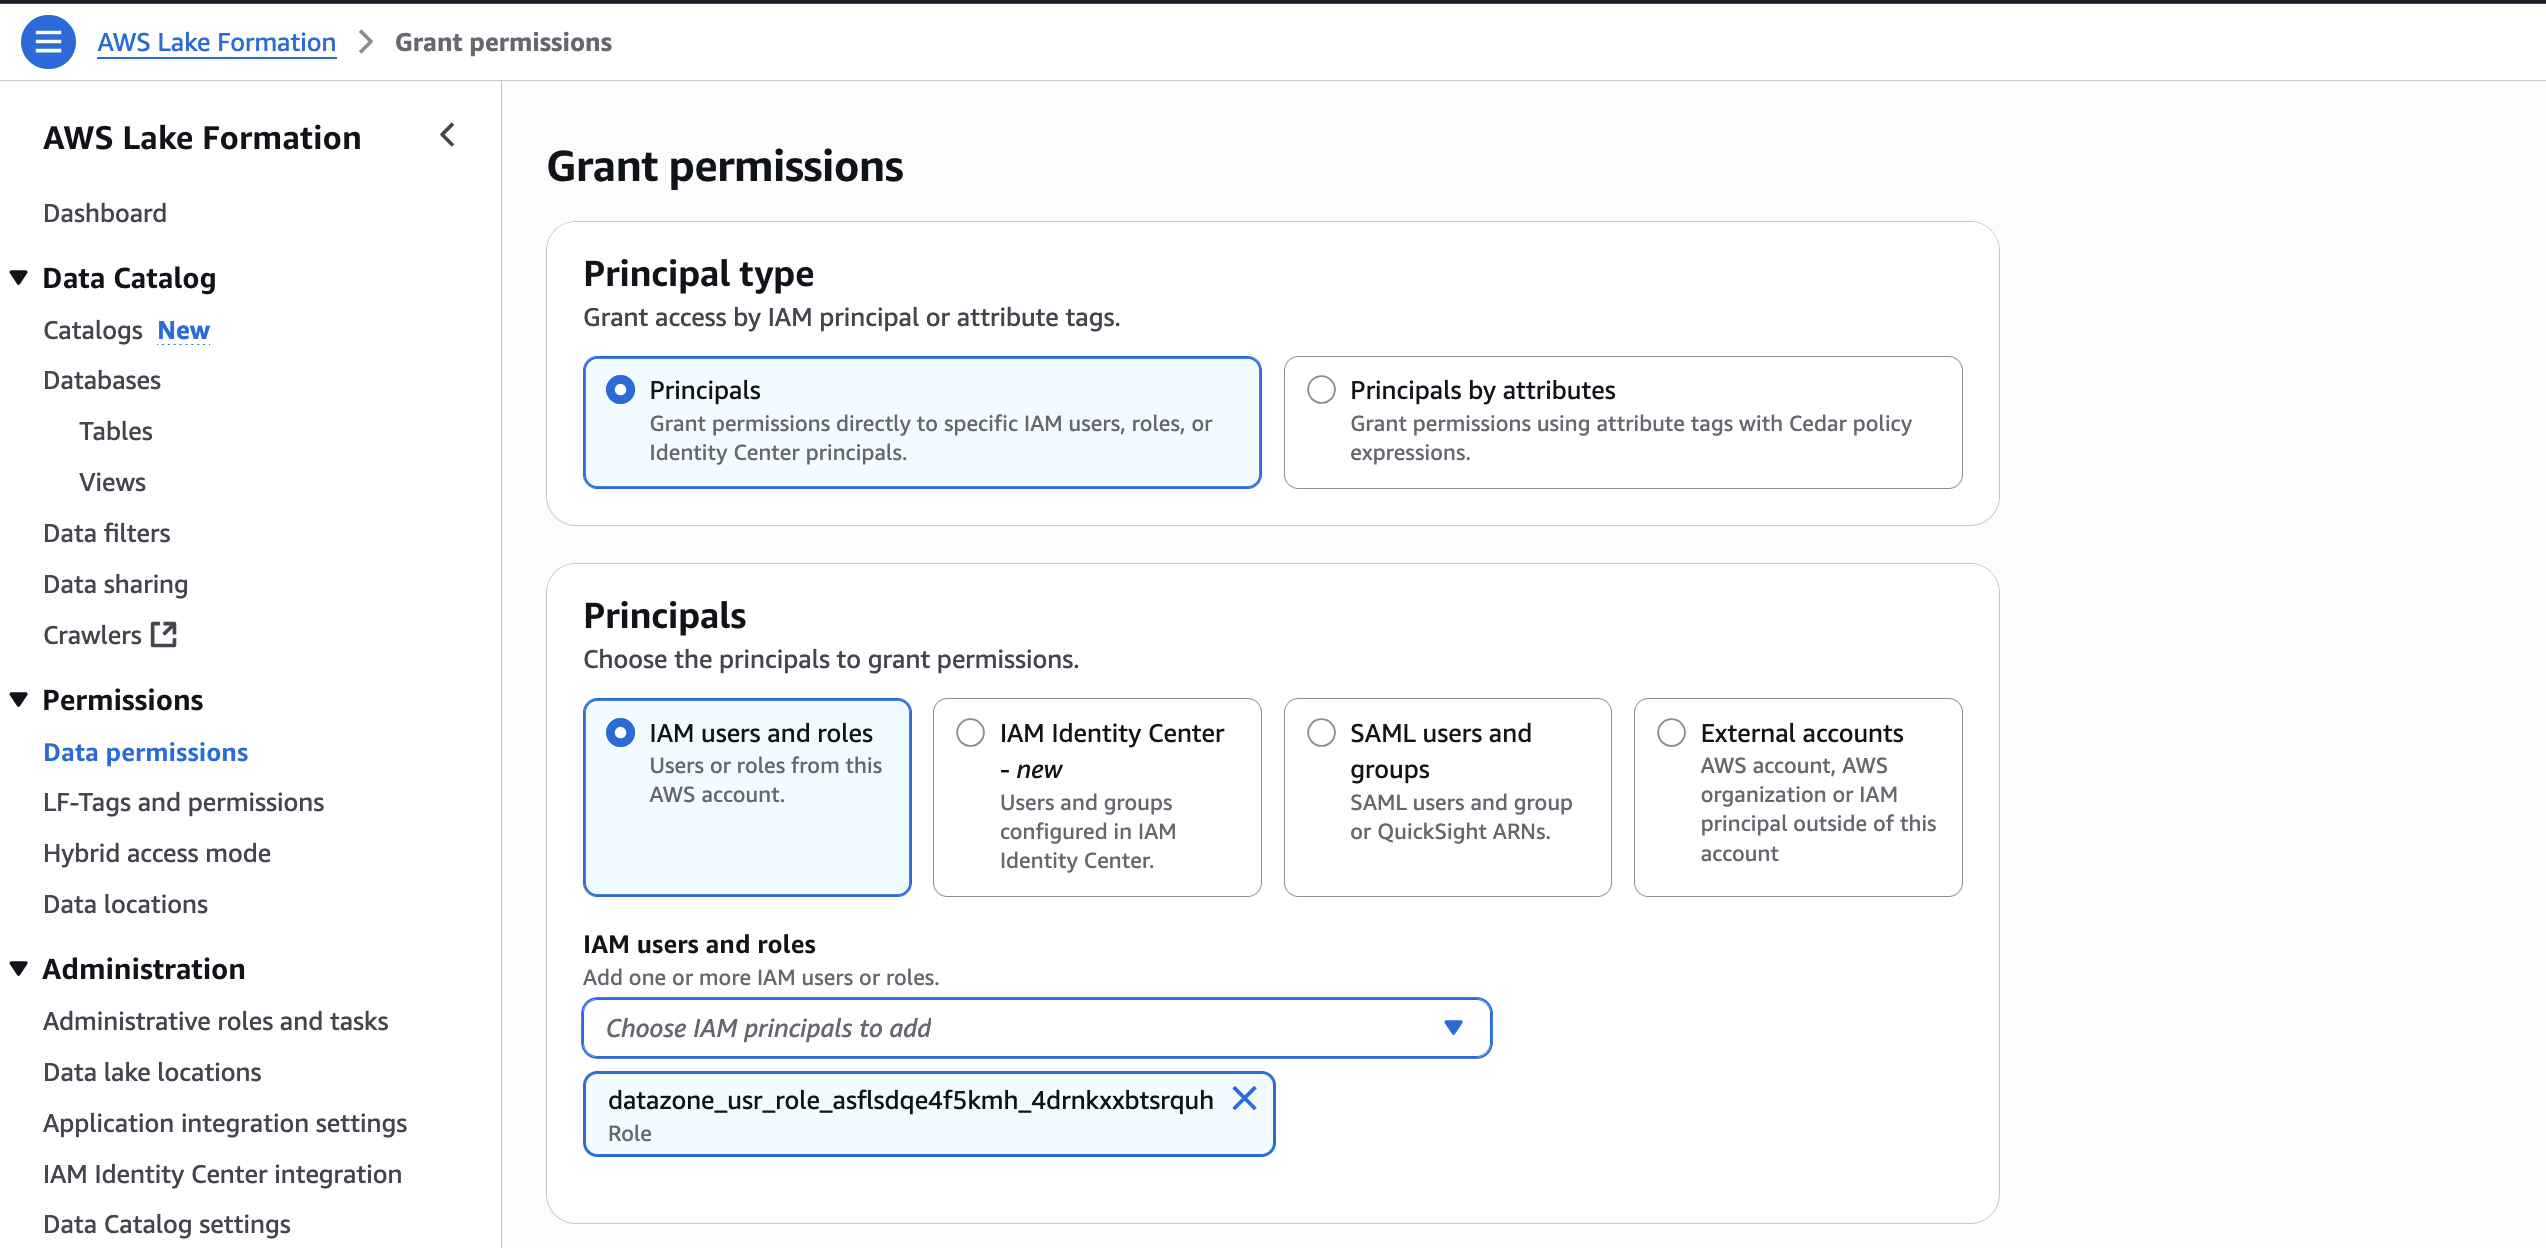
  1. In the AWS Lake Formation console, choose Permissions, choose Data permissions, and then choose Grant.
  2. Choose Principals, select IAM users and roles, then select the role generated by the project producer-s3tables in Step 3.
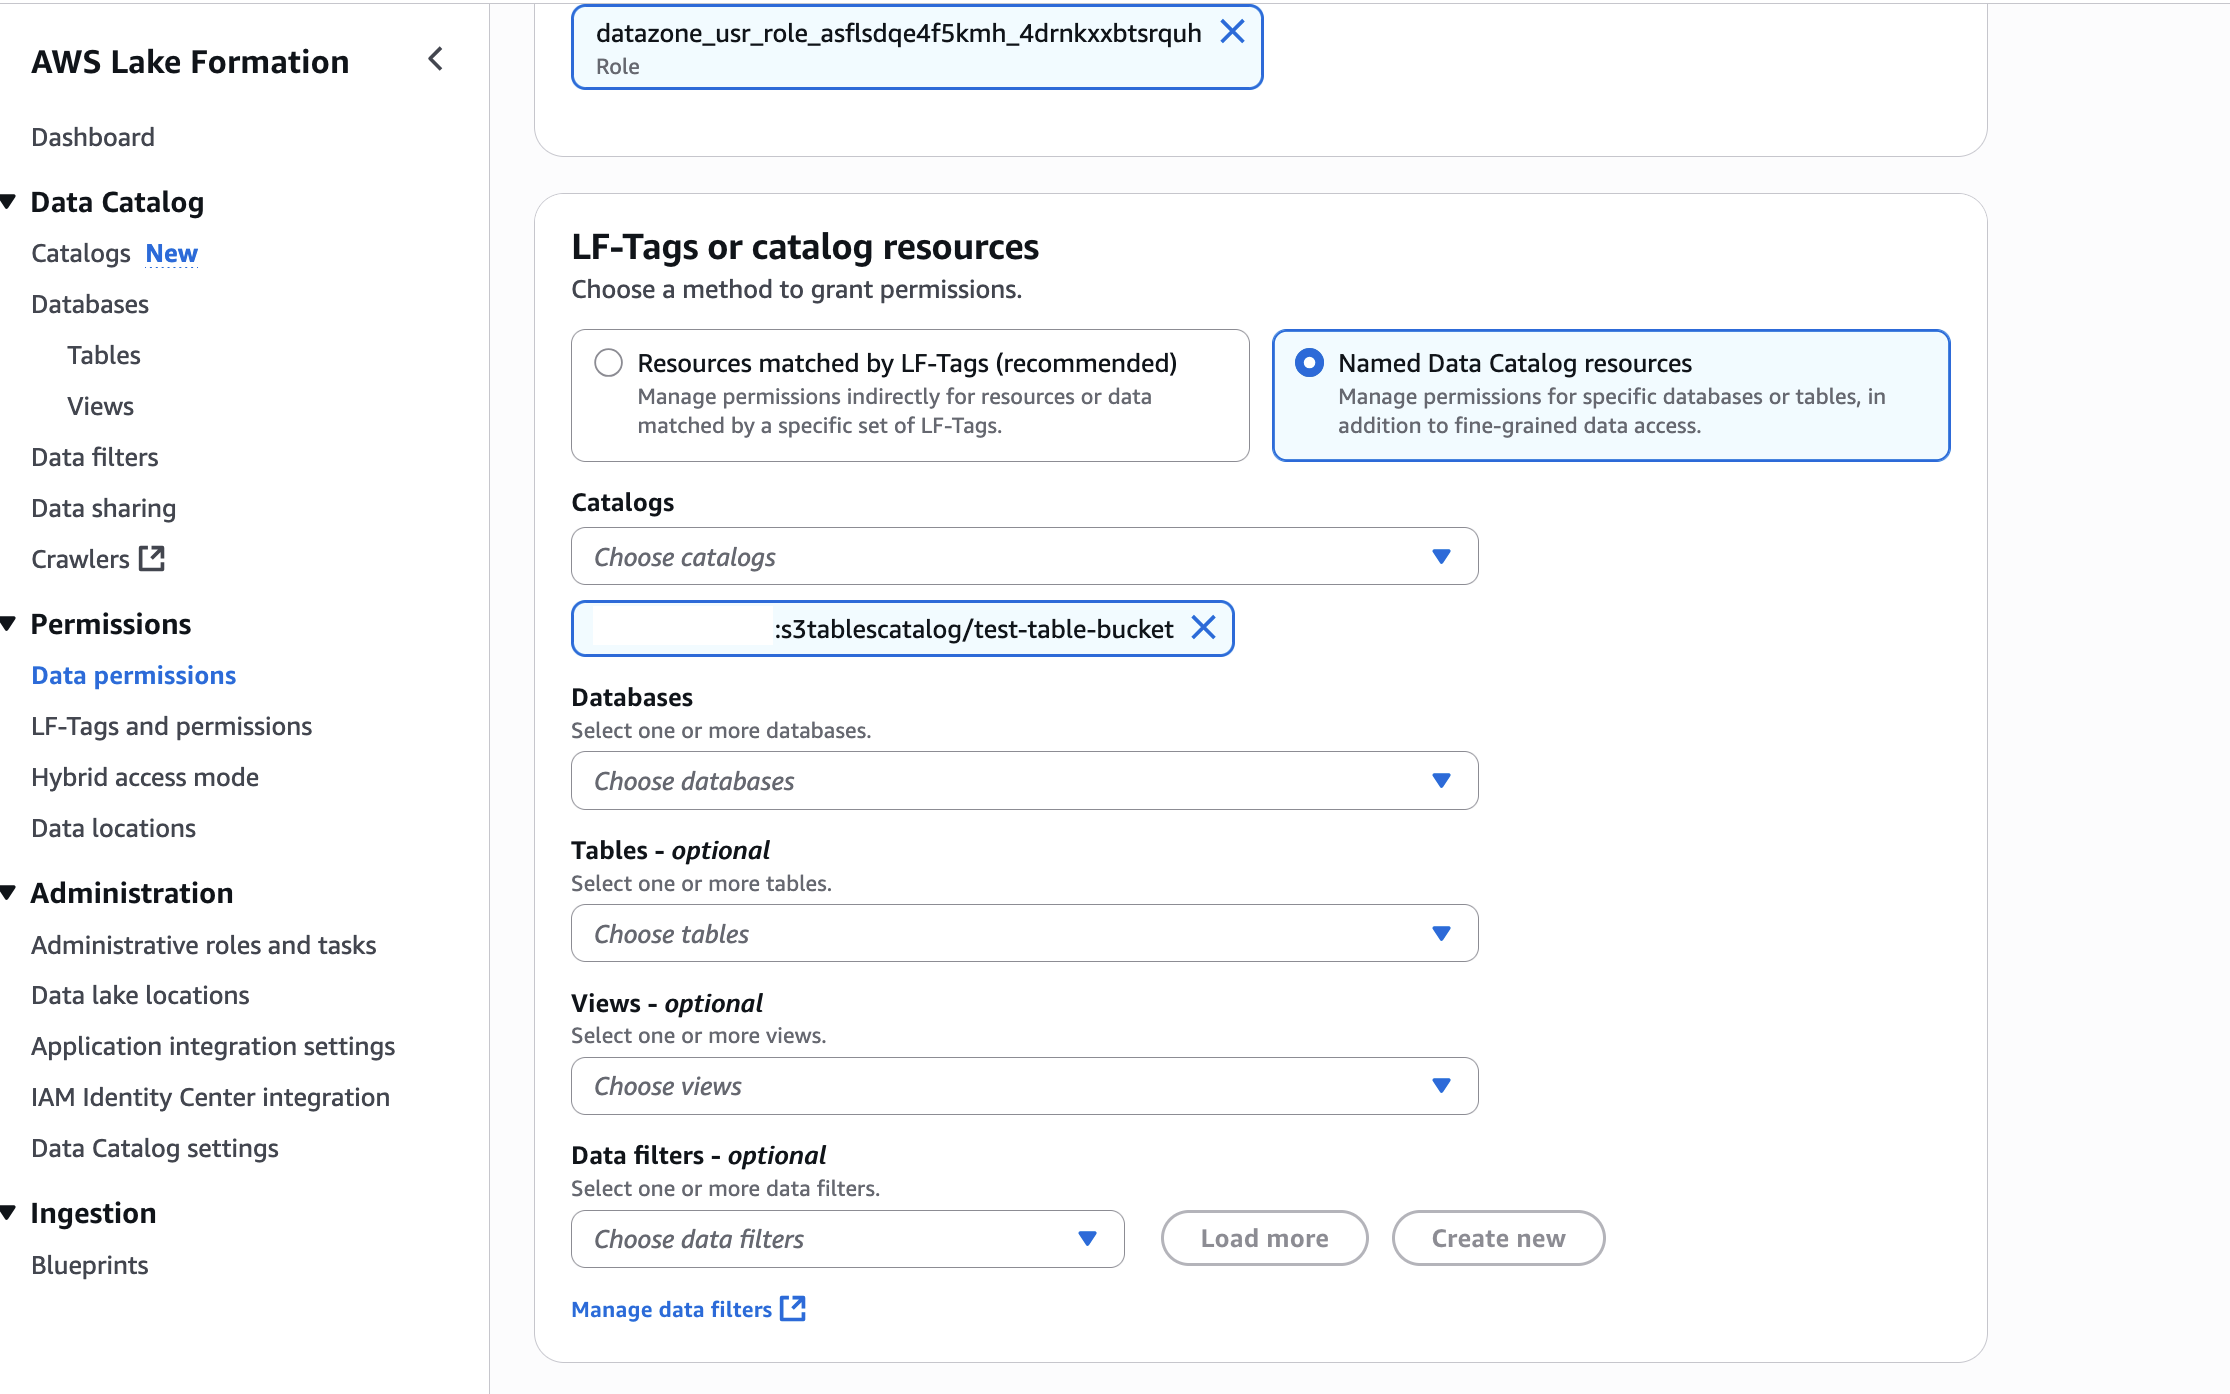
  3. In LF-Tags or catalog resources, choose Named data catalog resources, select the S3 table catalog from the Catalogs list.
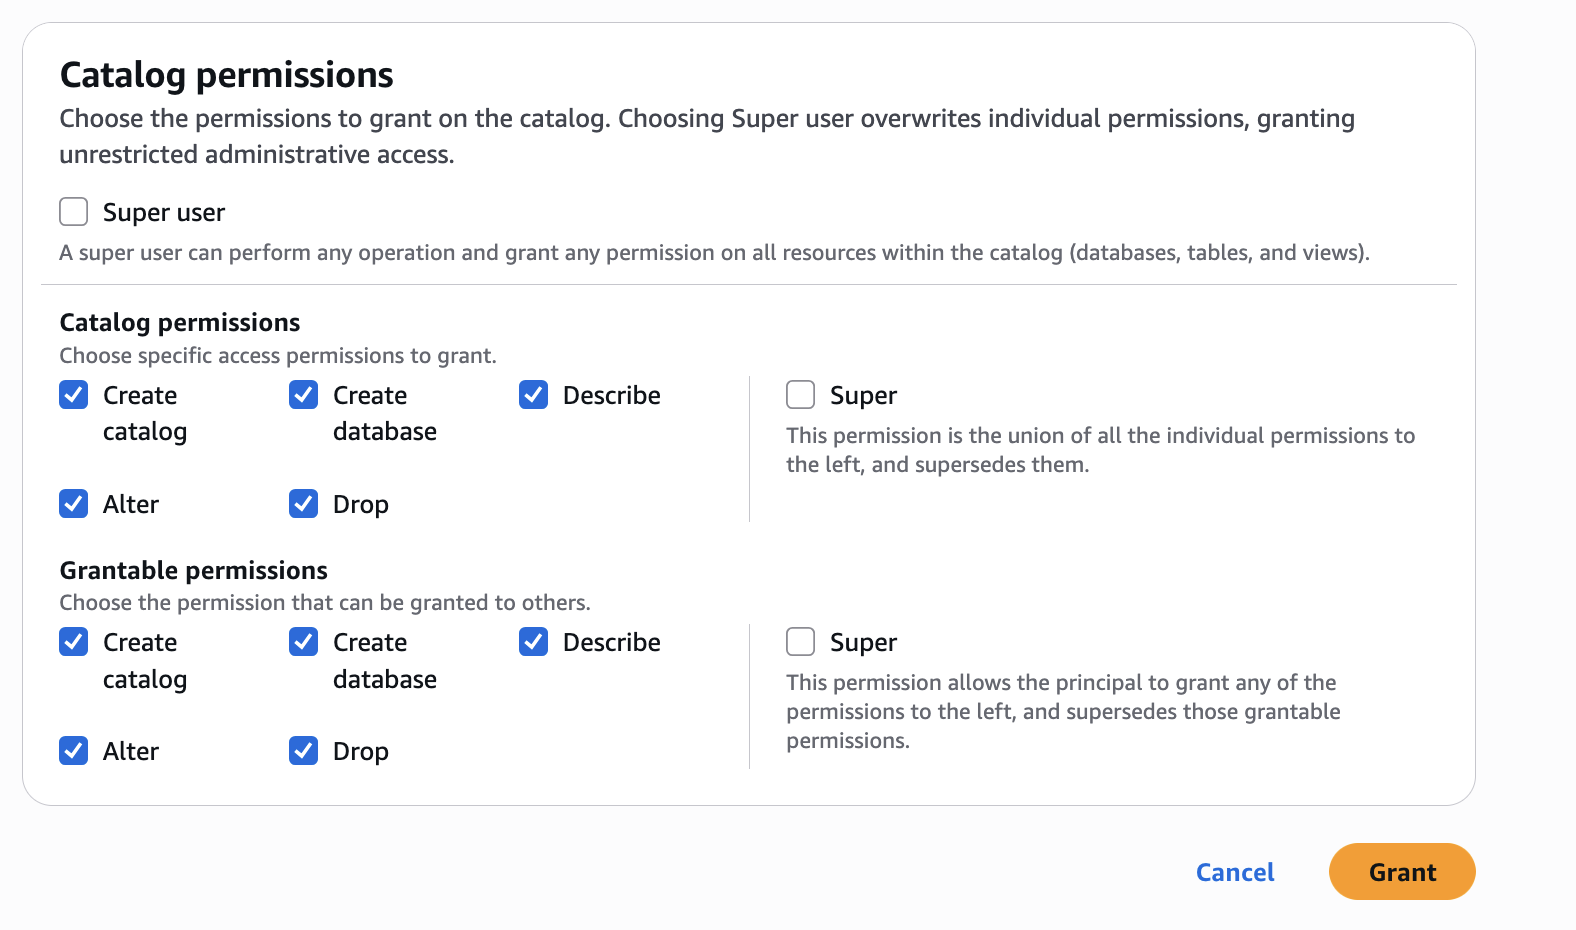
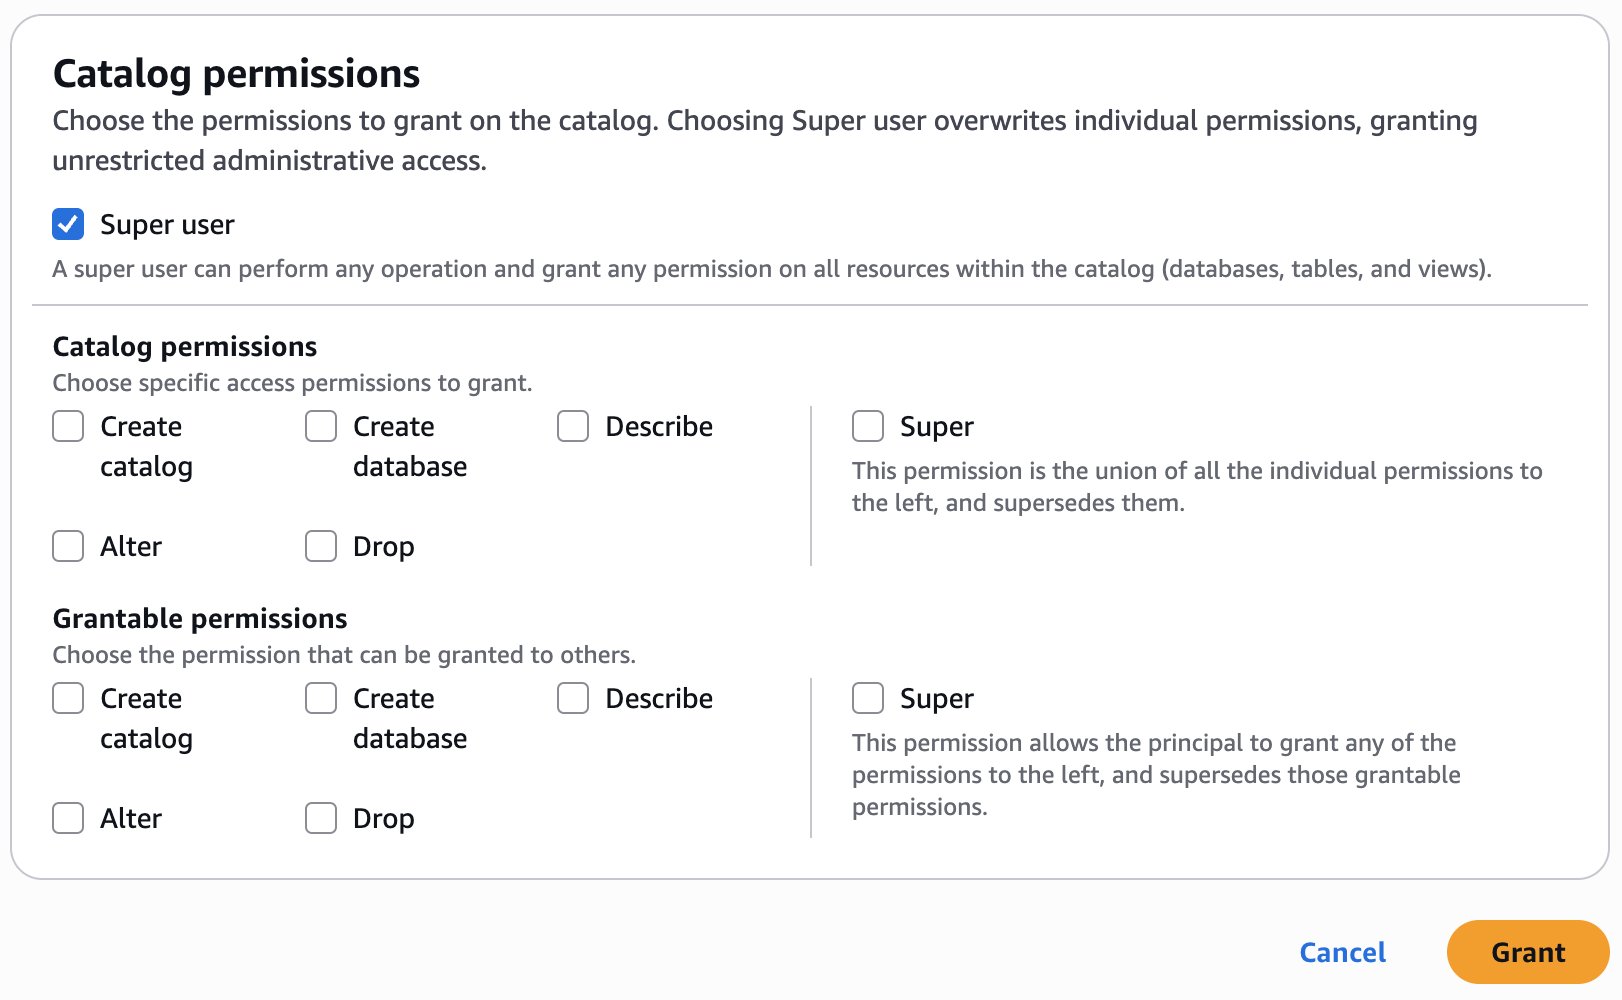
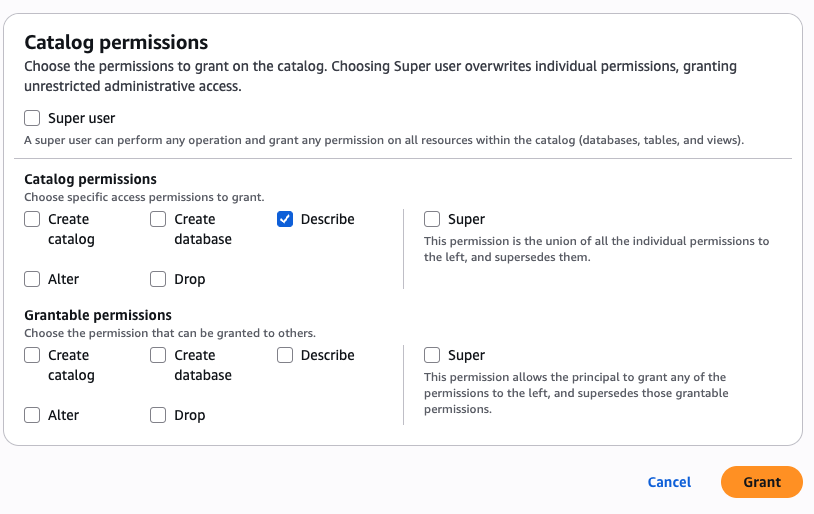
  4. In Catalog permissions, configure the Catalog permissions and grantable permissions. Choose Grant to apply the following permissions.

In Account A, we repeat these steps for grant permissions to the database:

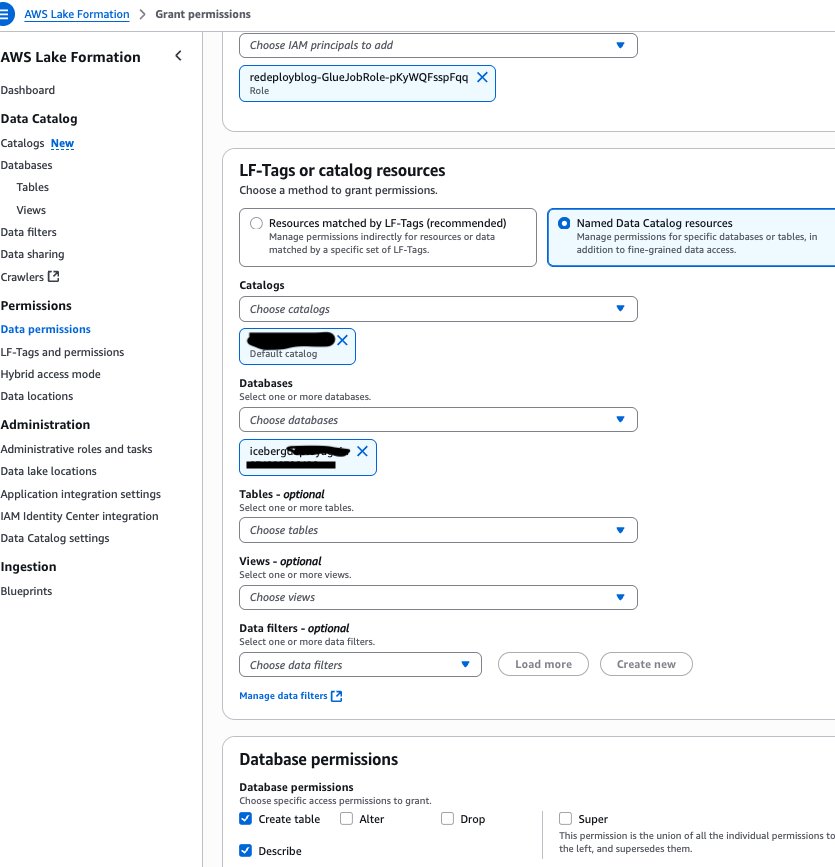
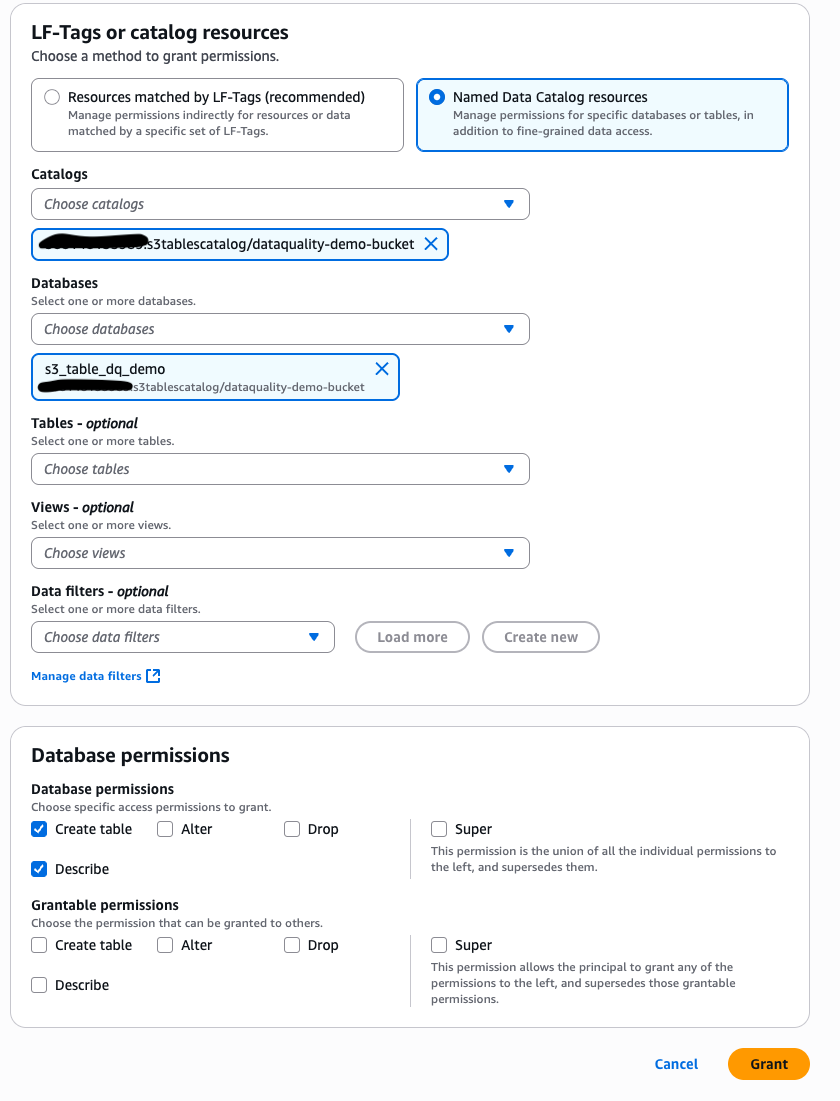
  1. In the AWS Lake Formation console, choose Permissions, choose Data permissions, and then choose Grant.
  2. Choose Principals, select IAM users and roles, then select the role generated by the project producer-s3tables in Step 3.
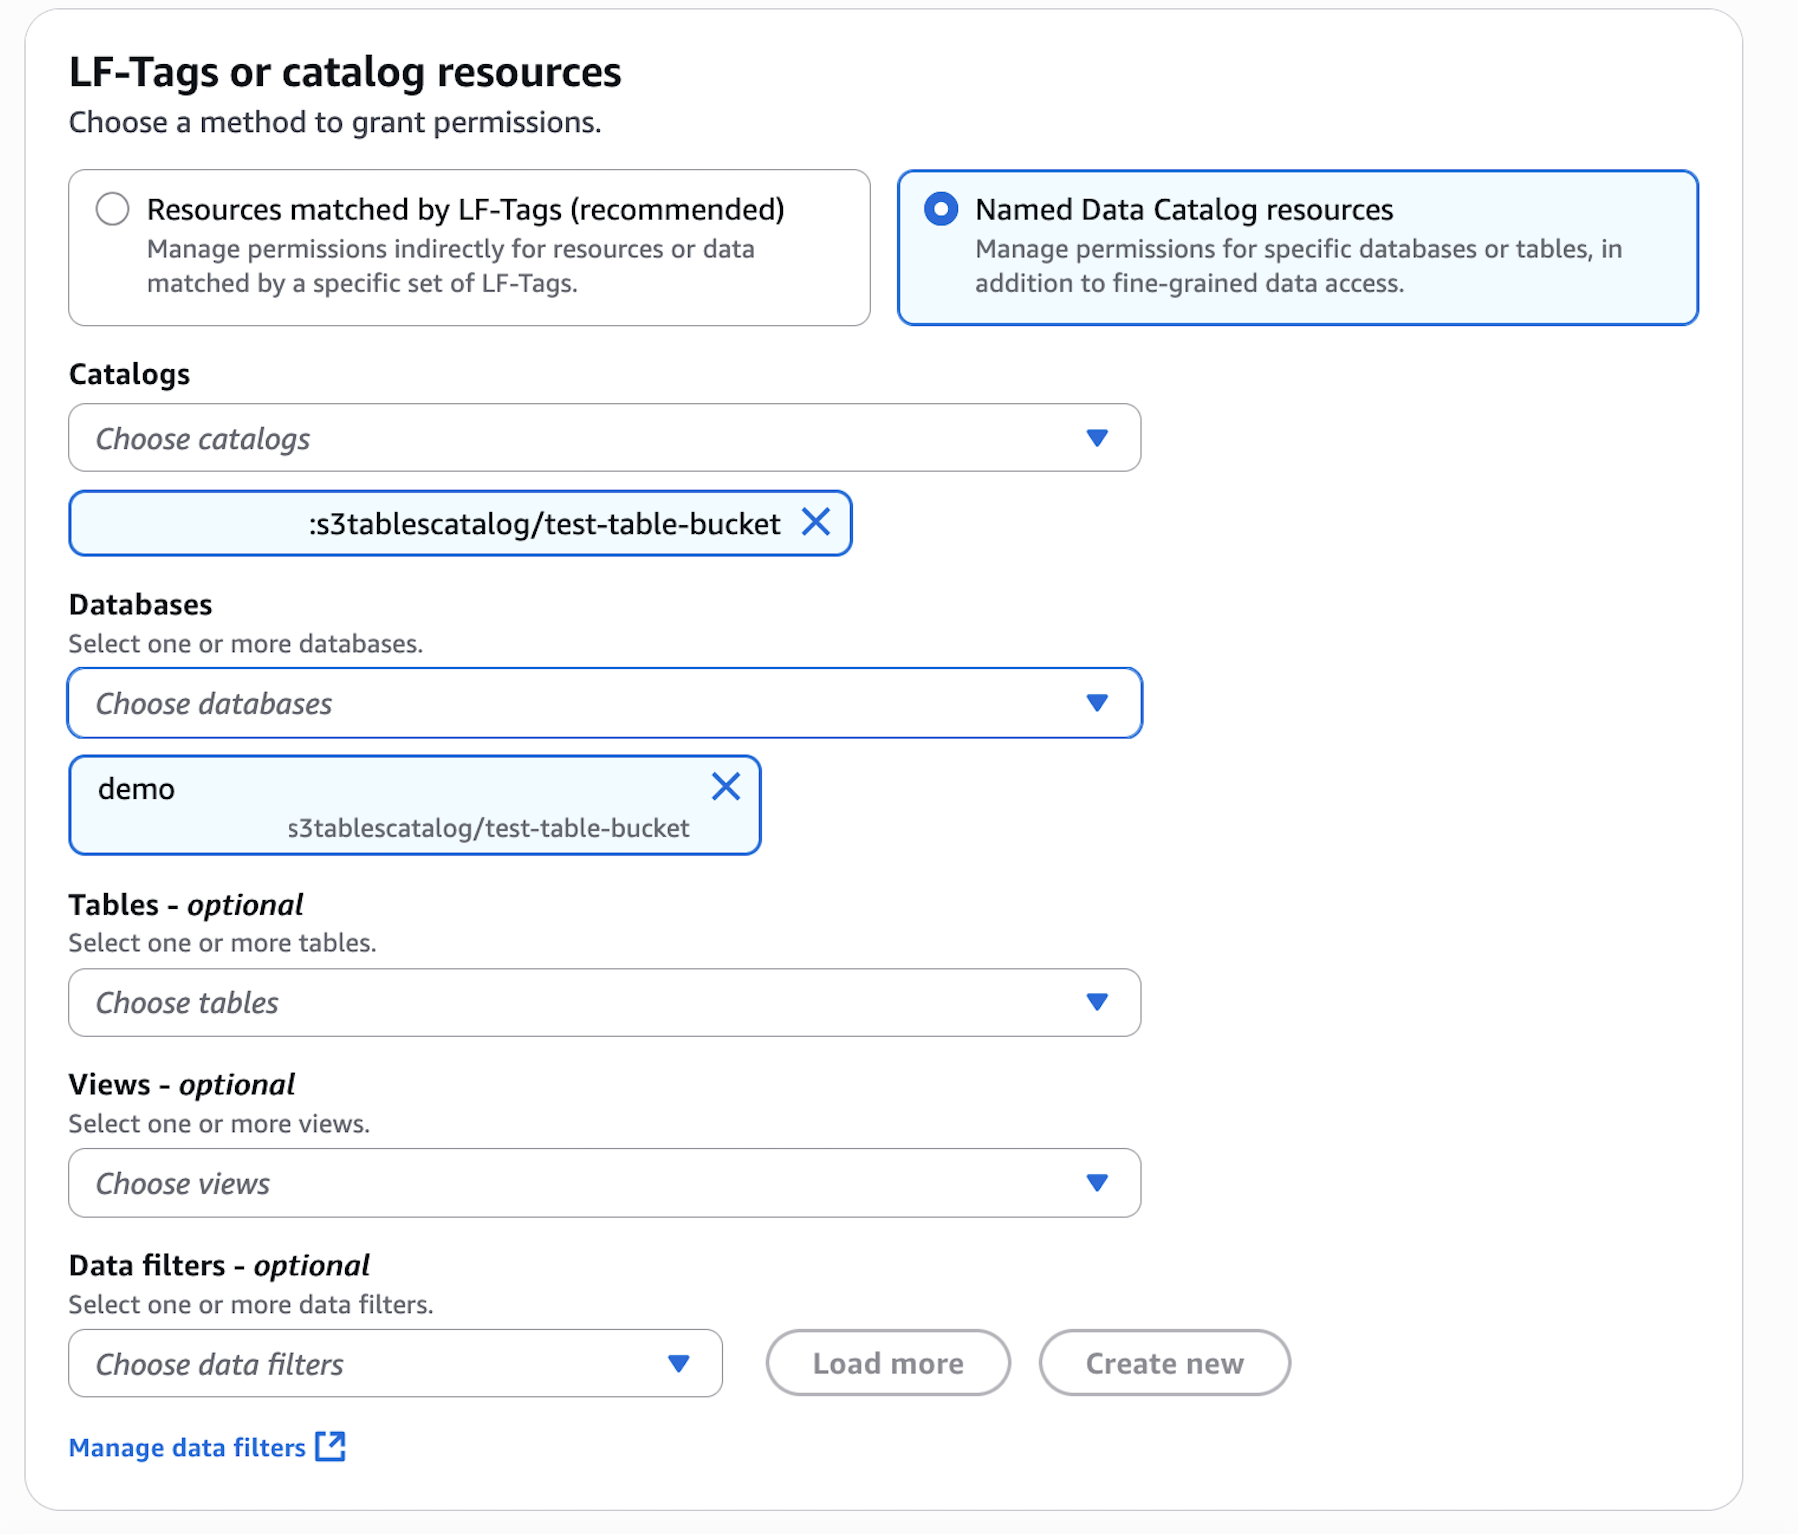
  3. In LF-Tags or catalog resources, choose Named data catalog resources, choose both the S3 table catalog and database from their respective dropdown lists.
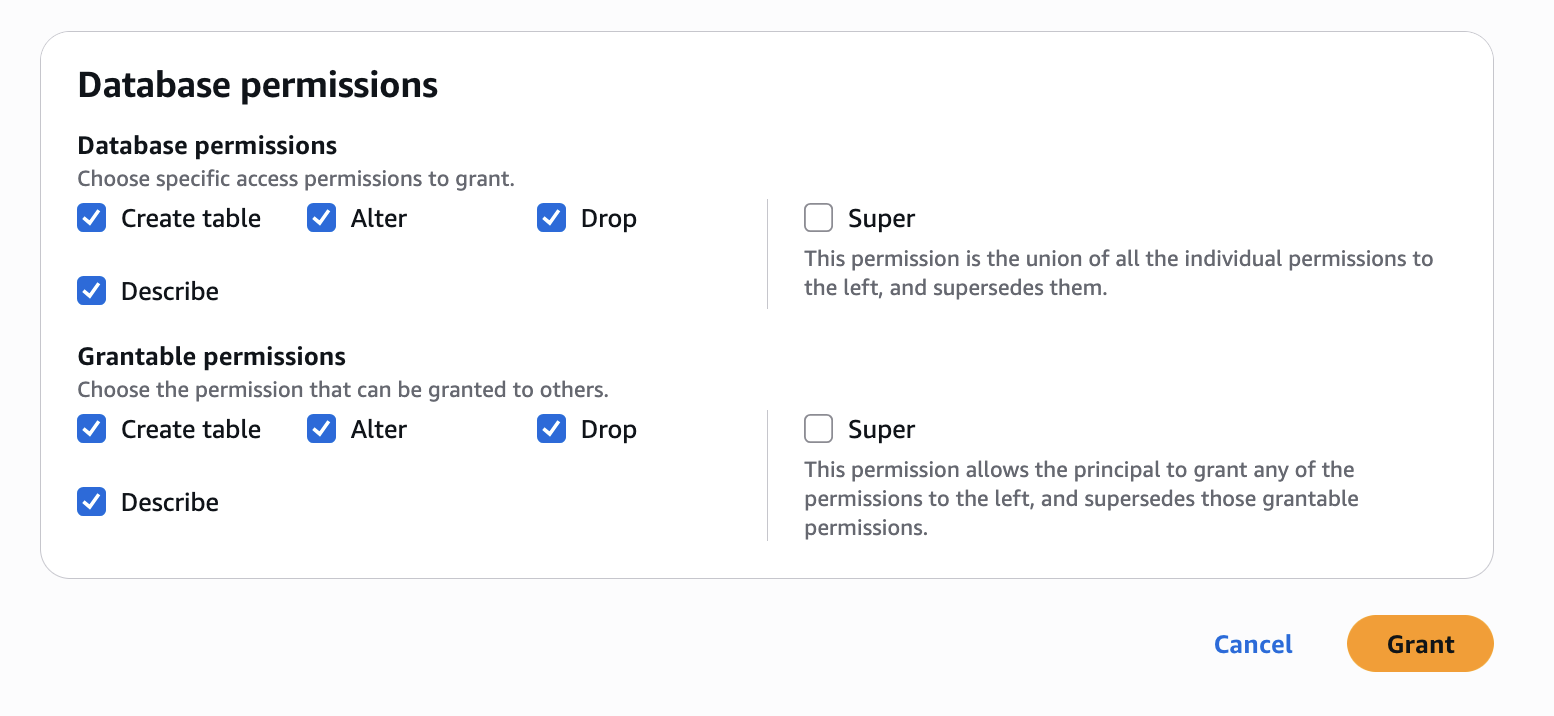
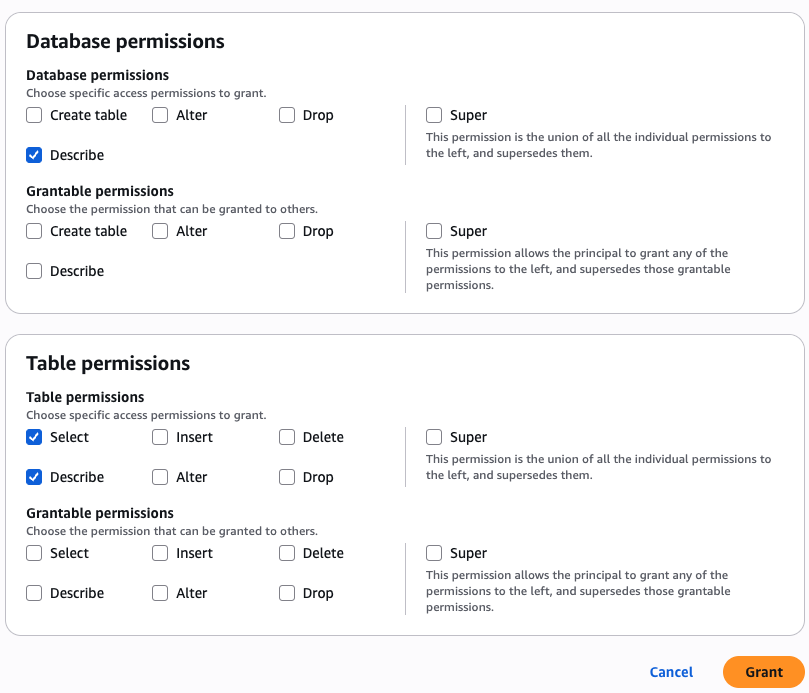
  4. Configure database permissions and grantable permissions. Choose Grant to apply the following permissions.

In Account A, repeat these steps for grant permissions to the table in the database:

  1. In the AWS Lake Formation console, choose Permissions, choose Data permissions, and then choose Grant.
  2. Choose Principals, select IAM users and roles, then select the role generated by the project producer-s3tables in Step 3.
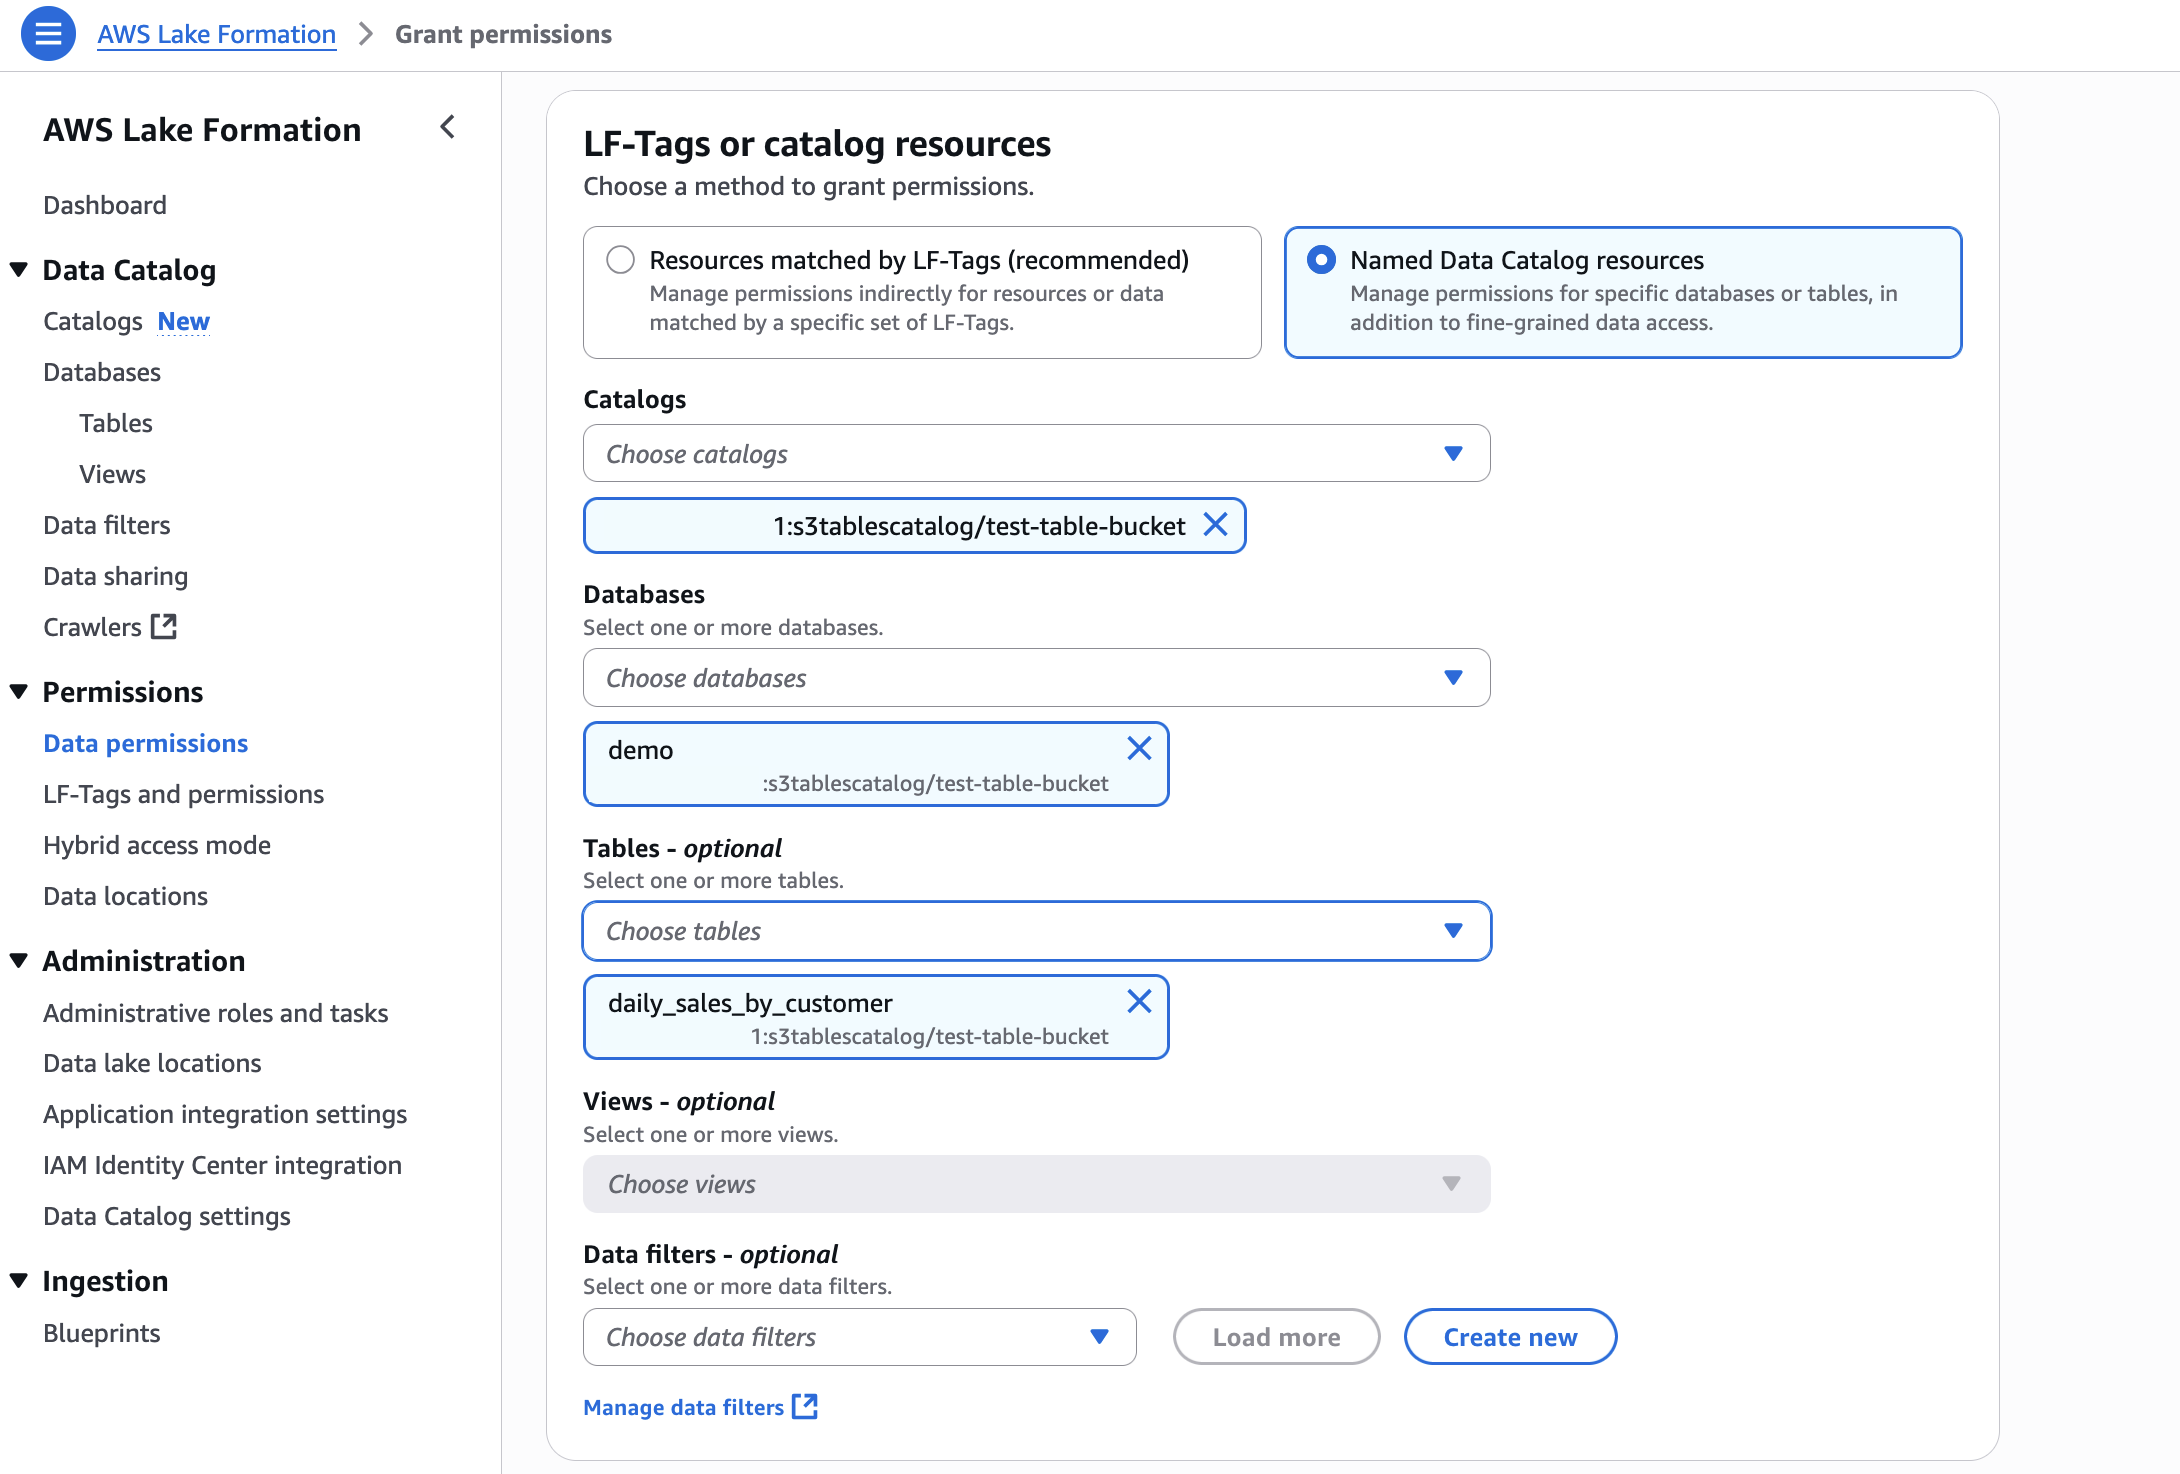
  3. In LF-Tags or catalog resources, choose Named data catalog resources, choose both the S3 table catalog, database, and S3 table from their respective dropdown lists.
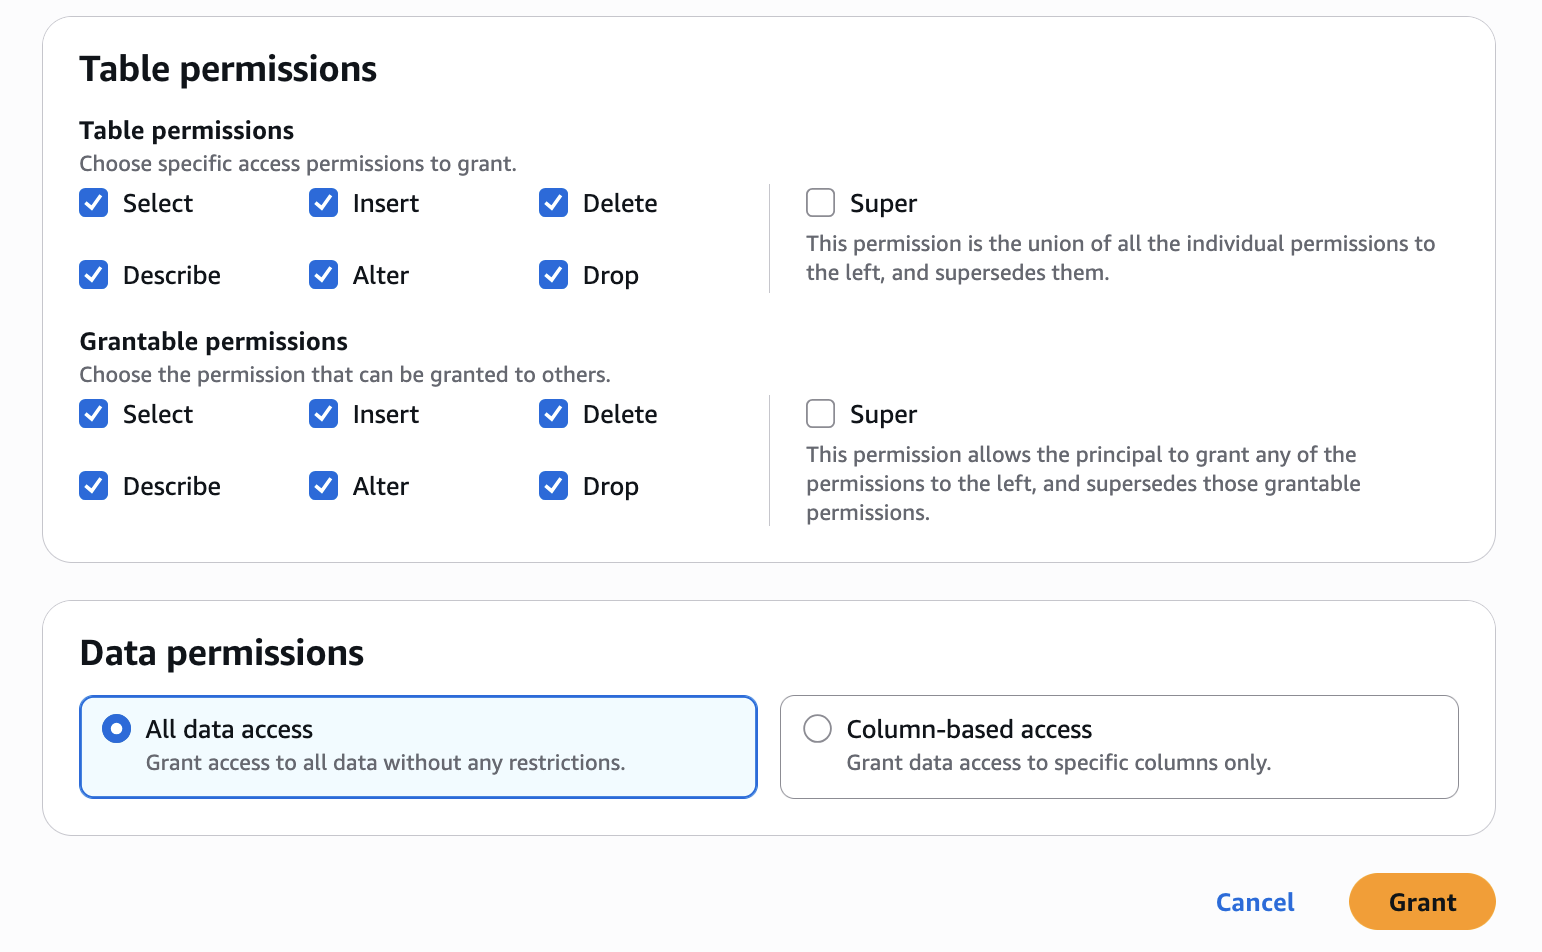
  4. Configure table permissions and grantable permissions. Choose Grant to apply the following permissions.

Repeat Step 4 in Accounts B to onboard S3 to SageMaker Lakehouse and grant the necessary permissions to the role created by your project for Account B.

Step 5: Create Datasource and onboard S3 Table from Account A and Glue Catalog Tables from Account B

To enable unified access and cross-account analytics with data lineage tracking, you’ll connect your SageMaker Unified Studio project to S3 tables from both accounts:

  1. Navigate to your project in SageMaker Unified Studio, select Data sources under the Project catalog section and choose Create data source.
  2. Enter a name, description, and select AWS Glue as the Data source type. Under Data selection, specify the S3 table catalog name.
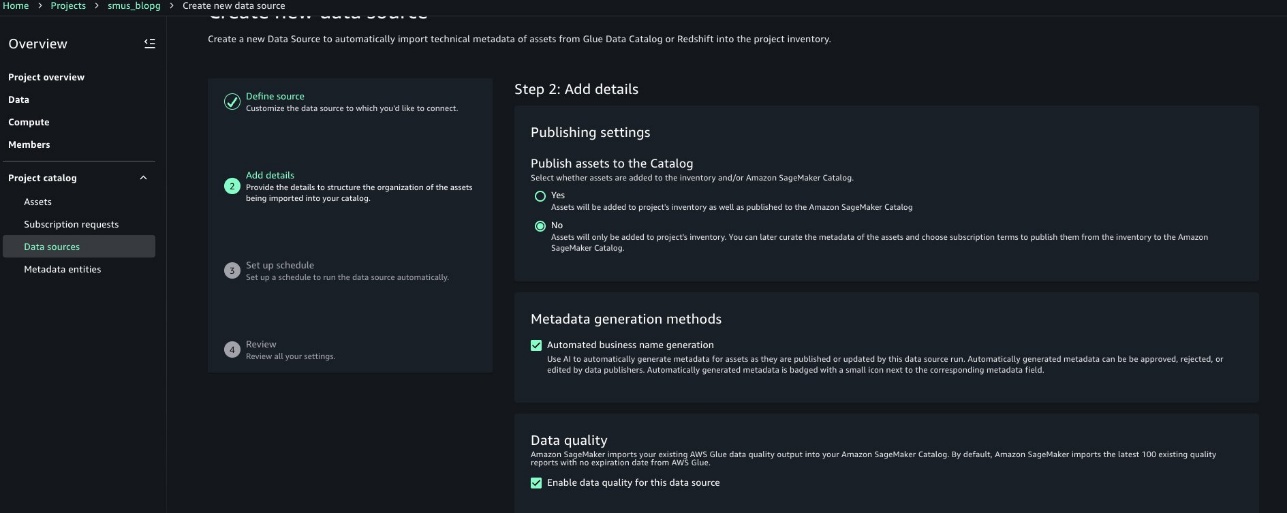
  3. In this post, we will keep the Publishing setting and Metadata settings as the default configuration.
  4. Choose the run preference as Run on demand to manually initiate data source runs.
  5. Configure any optional connection settings, such as importing data lineage or setting up data quality options. Review your configuration and create the data source.
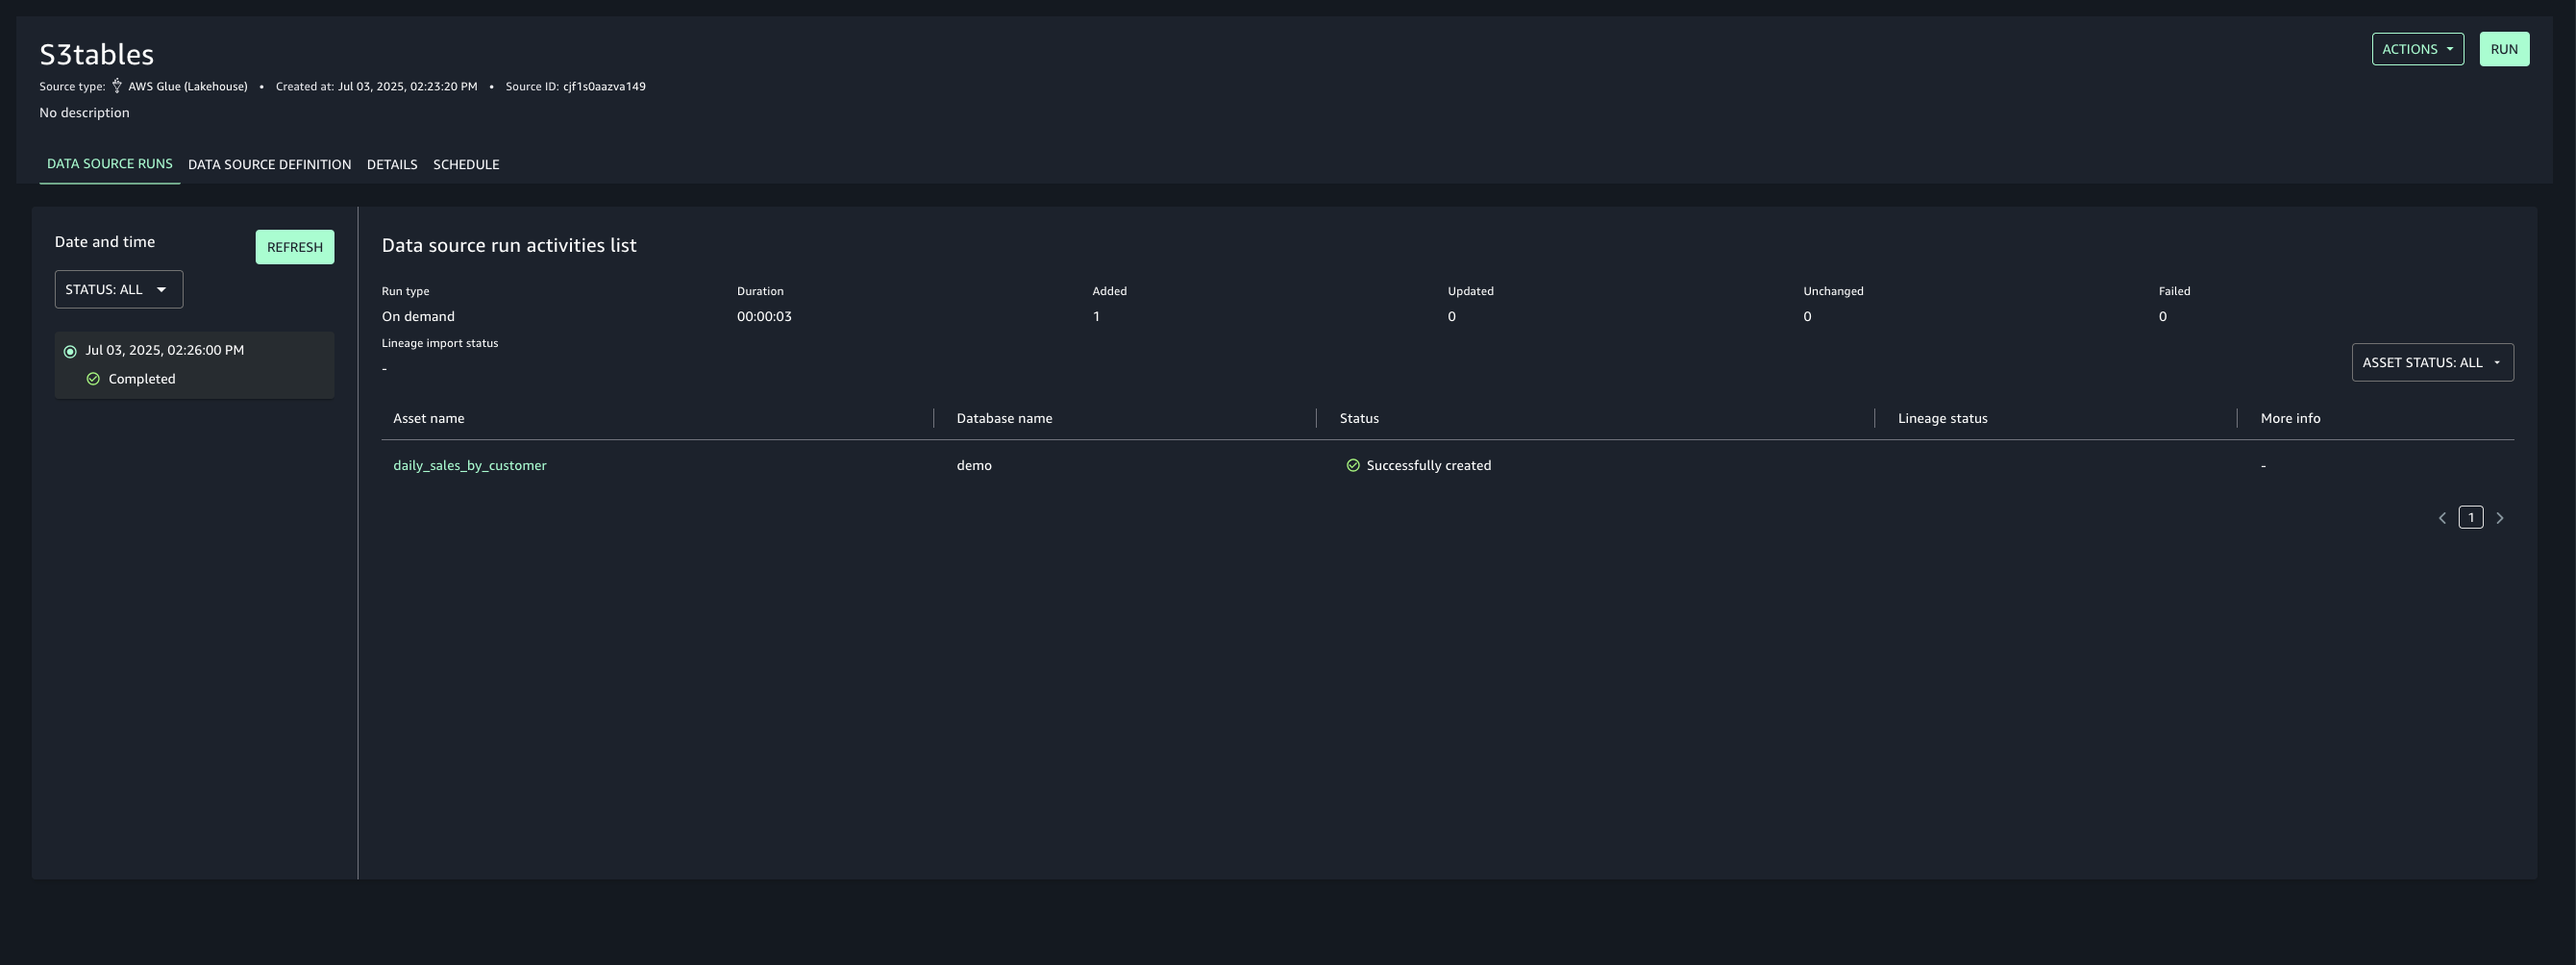
  6. Once created, run the data source to import the Glue assets into your project’s inventory.
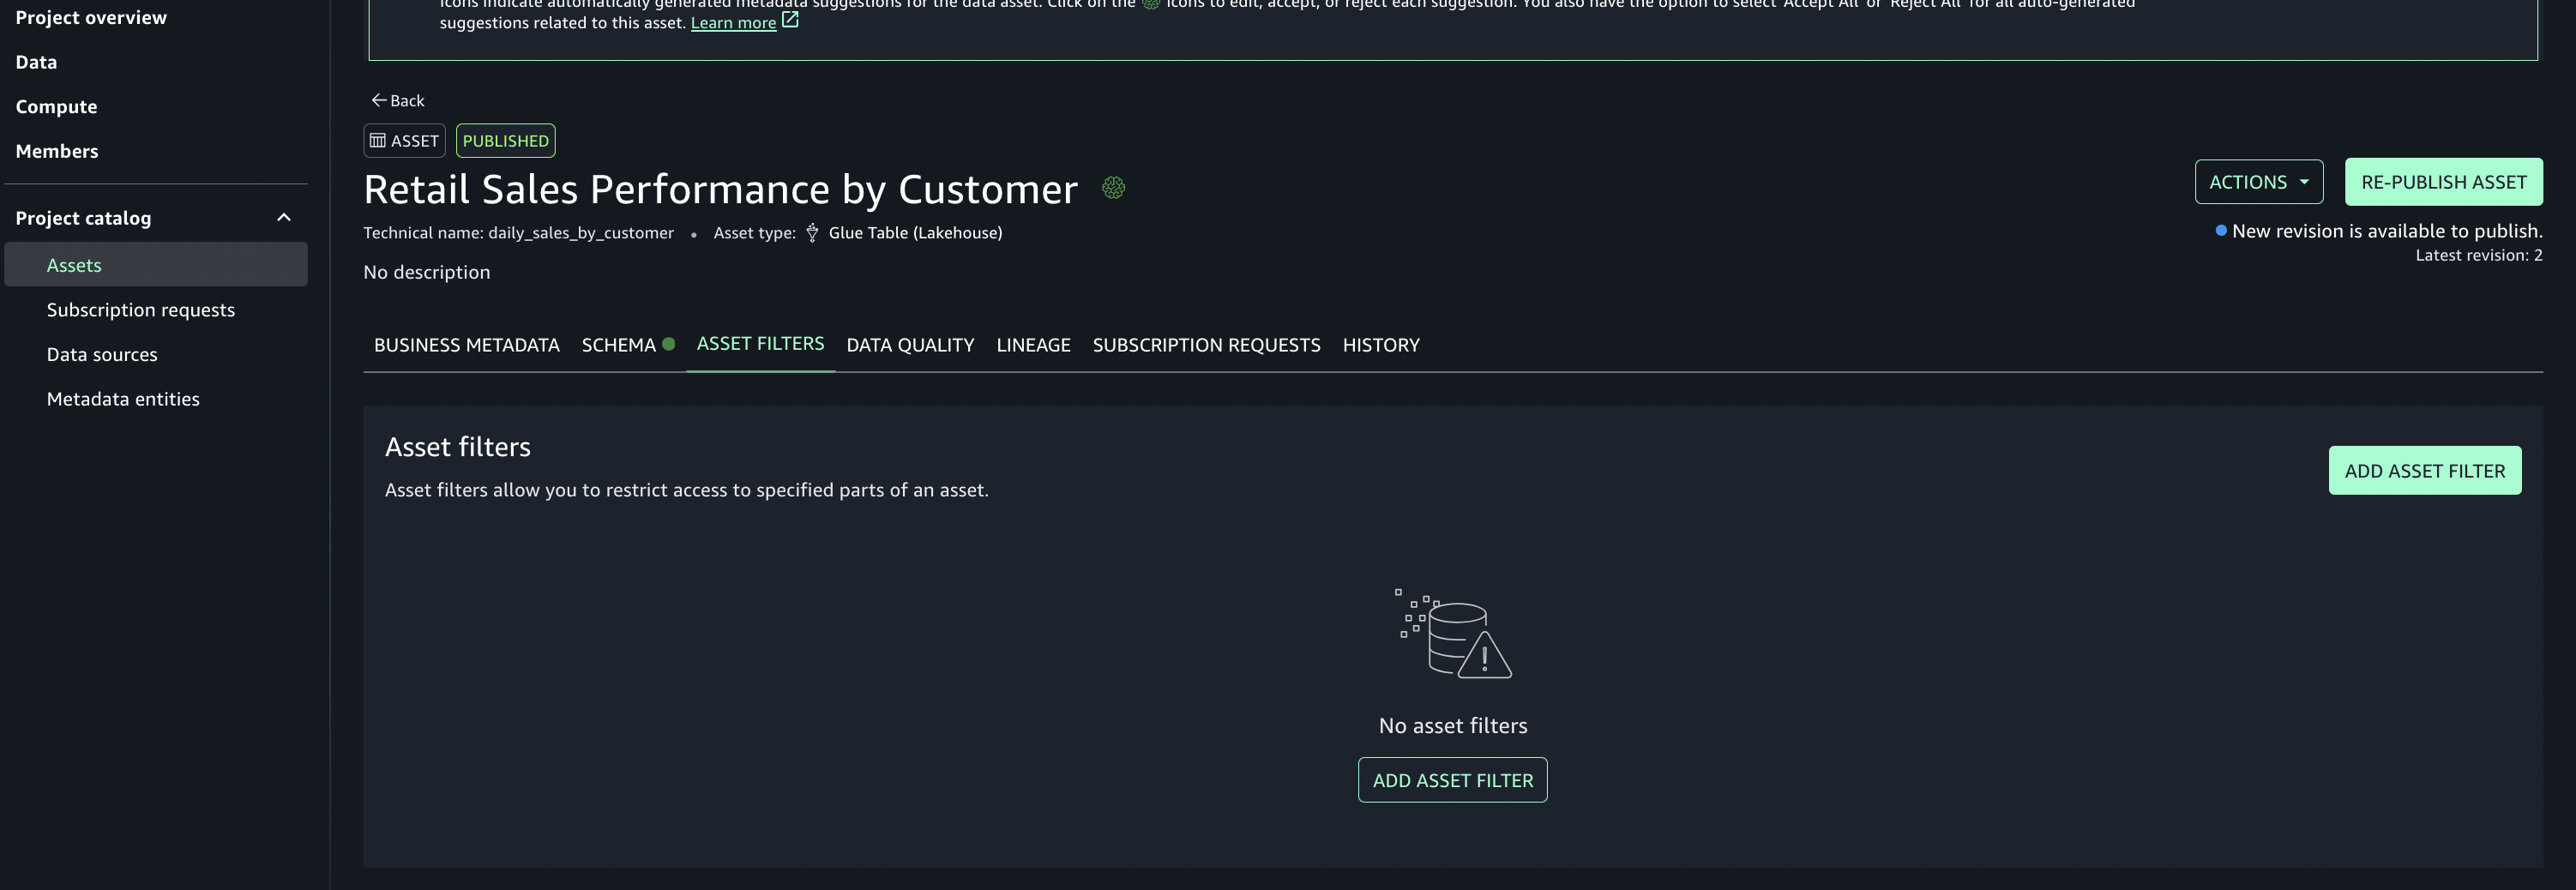
  7. Add asset filter to restrict consumer access, On the Asset filters tab, choose Add asset filter.
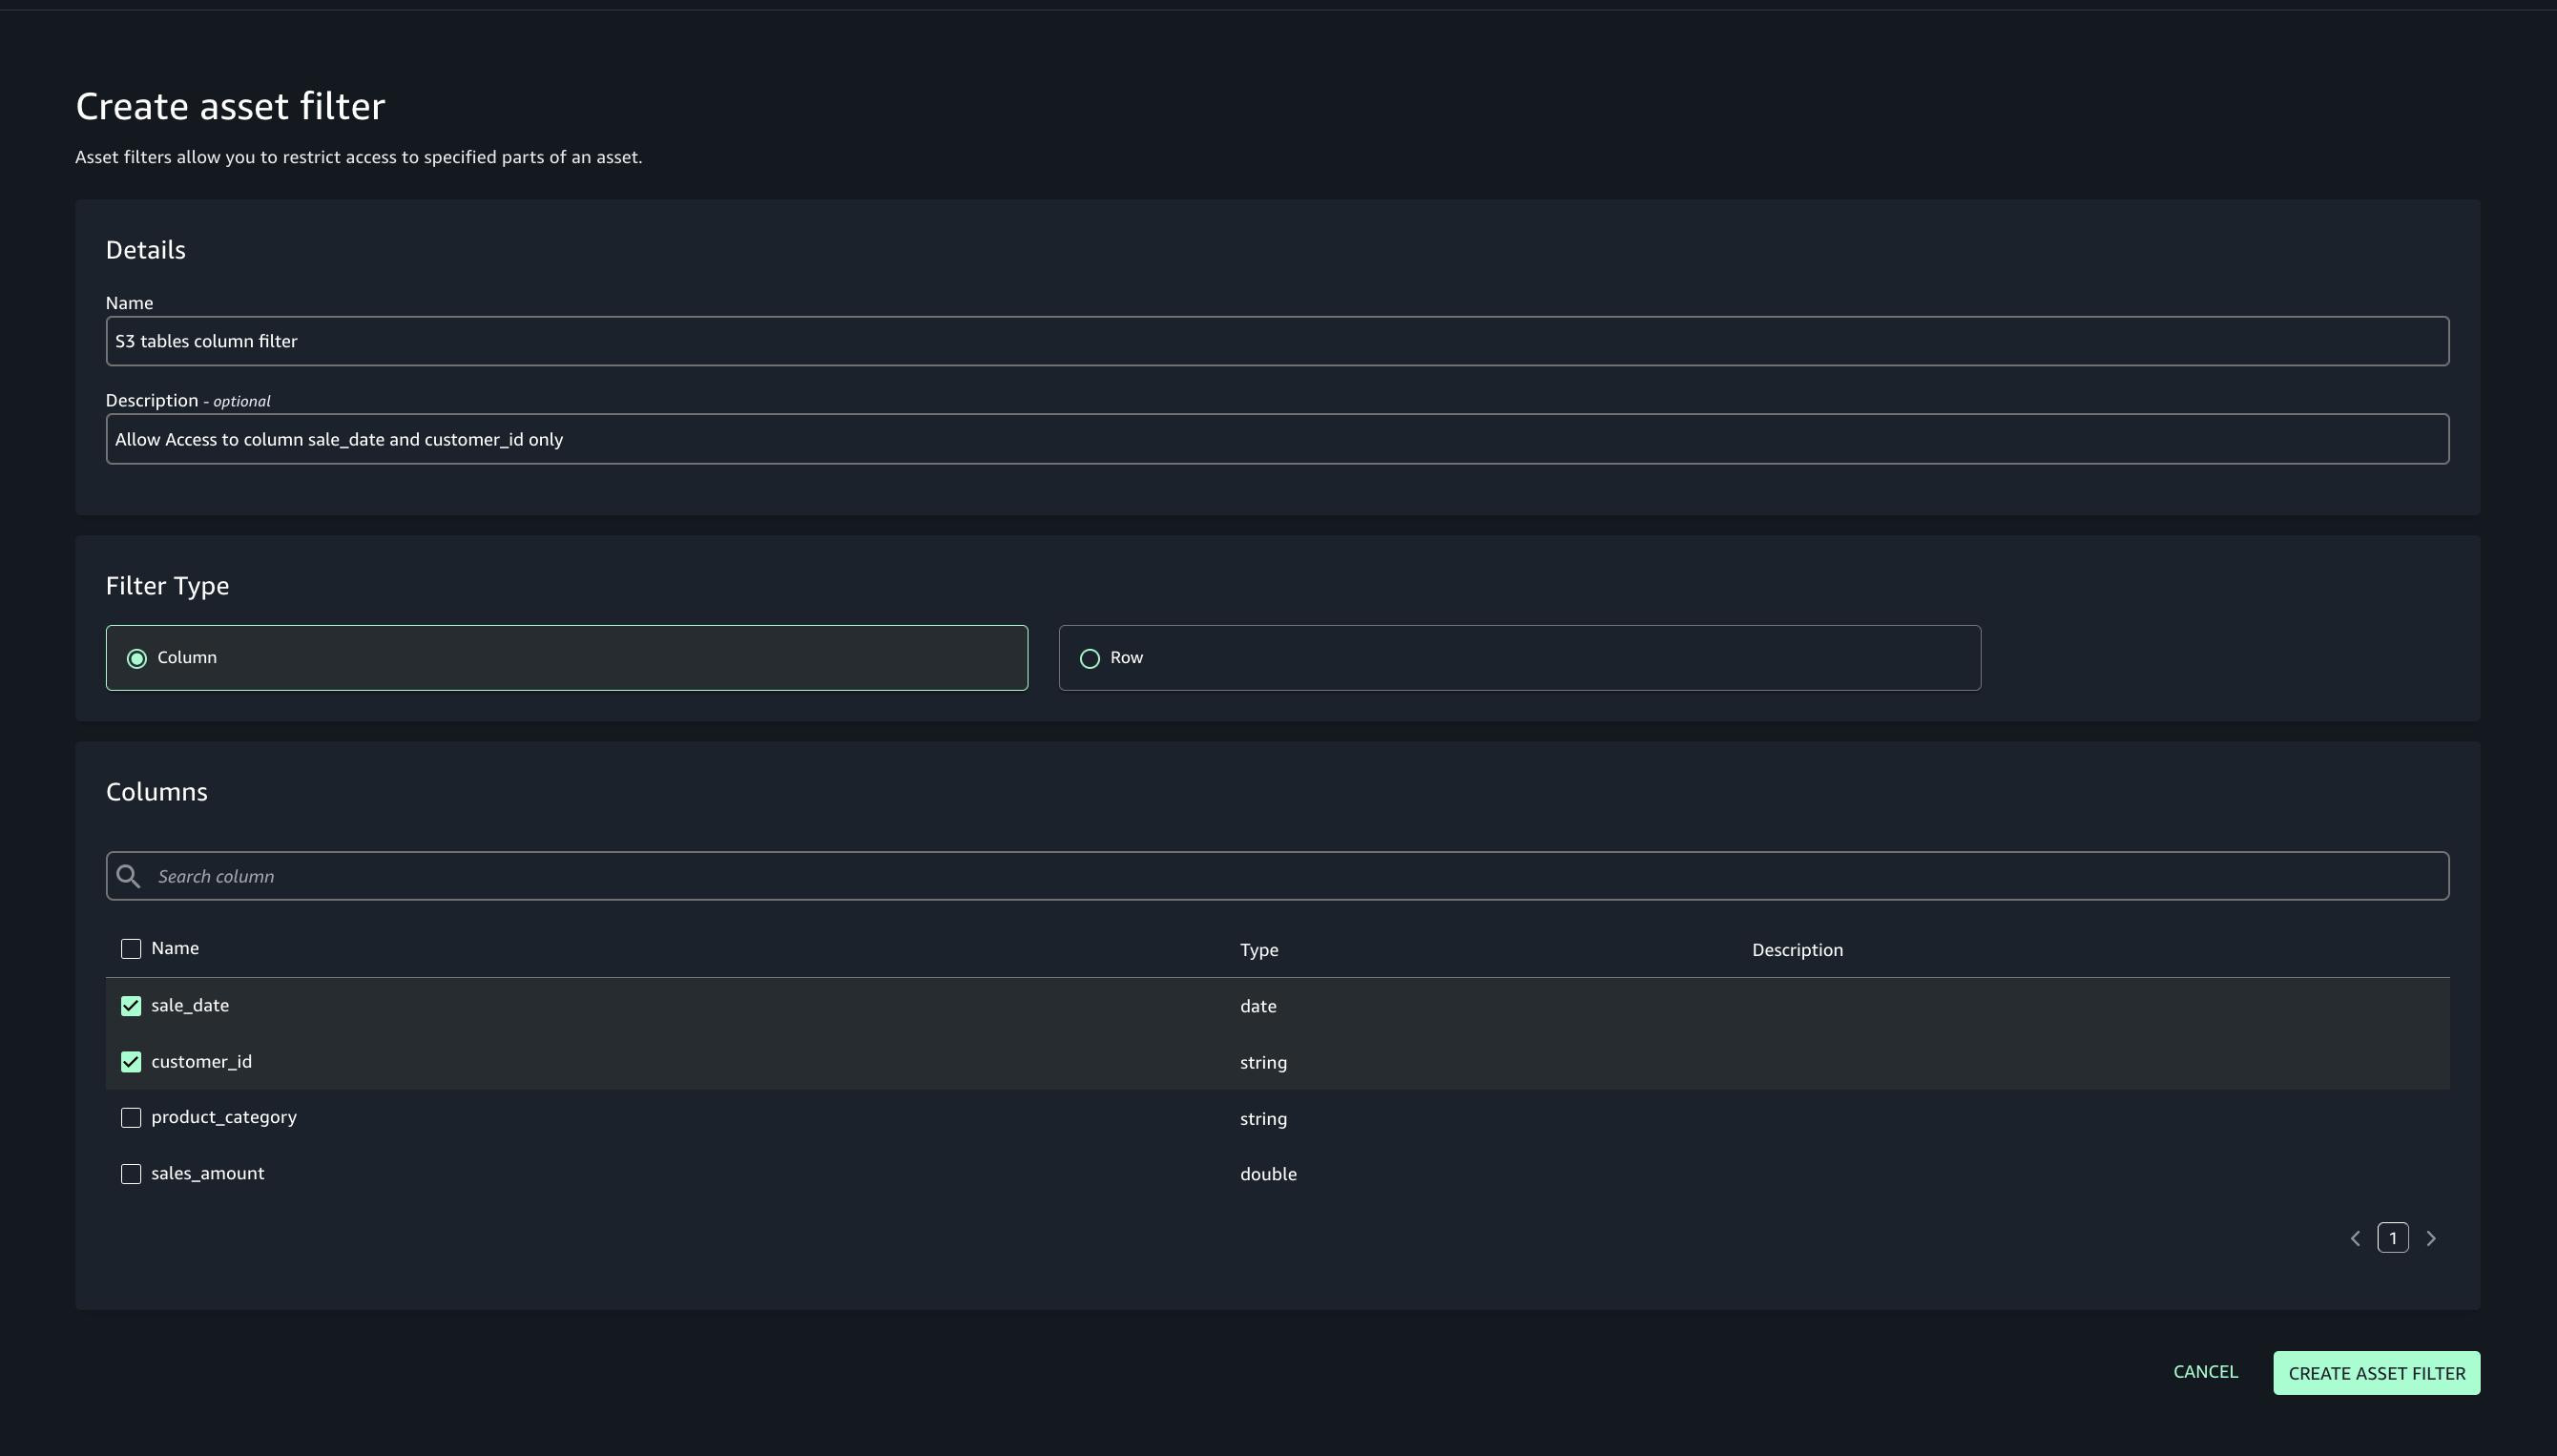
  8. Select Column as the filter type, choose the columns for consumer access, and create the asset filter.
  9. Select the assets created and choose Publish assets to the SageMaker Unified Studio catalog to make them discoverable by other users.
  10. Use the documentation to add Glue catalog as data source for S3.

Step 6: Subscribe to the asset from Consumer account in Account C

In Account C, enable the consumer teams to discover, request, and subscribe to those assets for secure, governed data sharing and collaboration across projects.

  1. In SageMaker Unified Studio, select the consumer project.
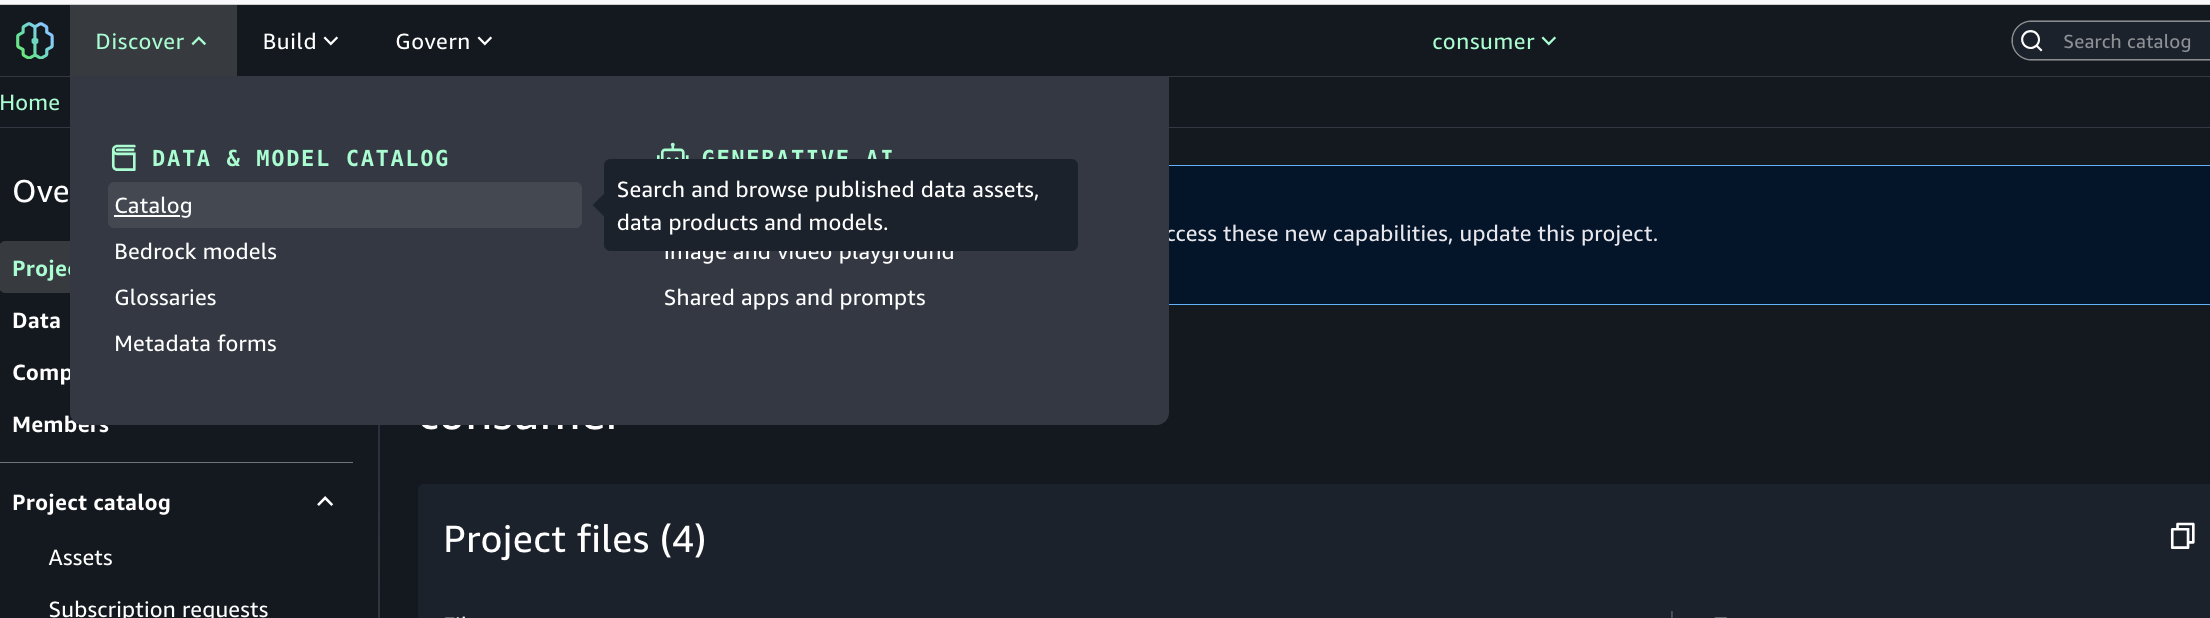
  2. Use the Discover menu (top navigation) and go to Catalog.
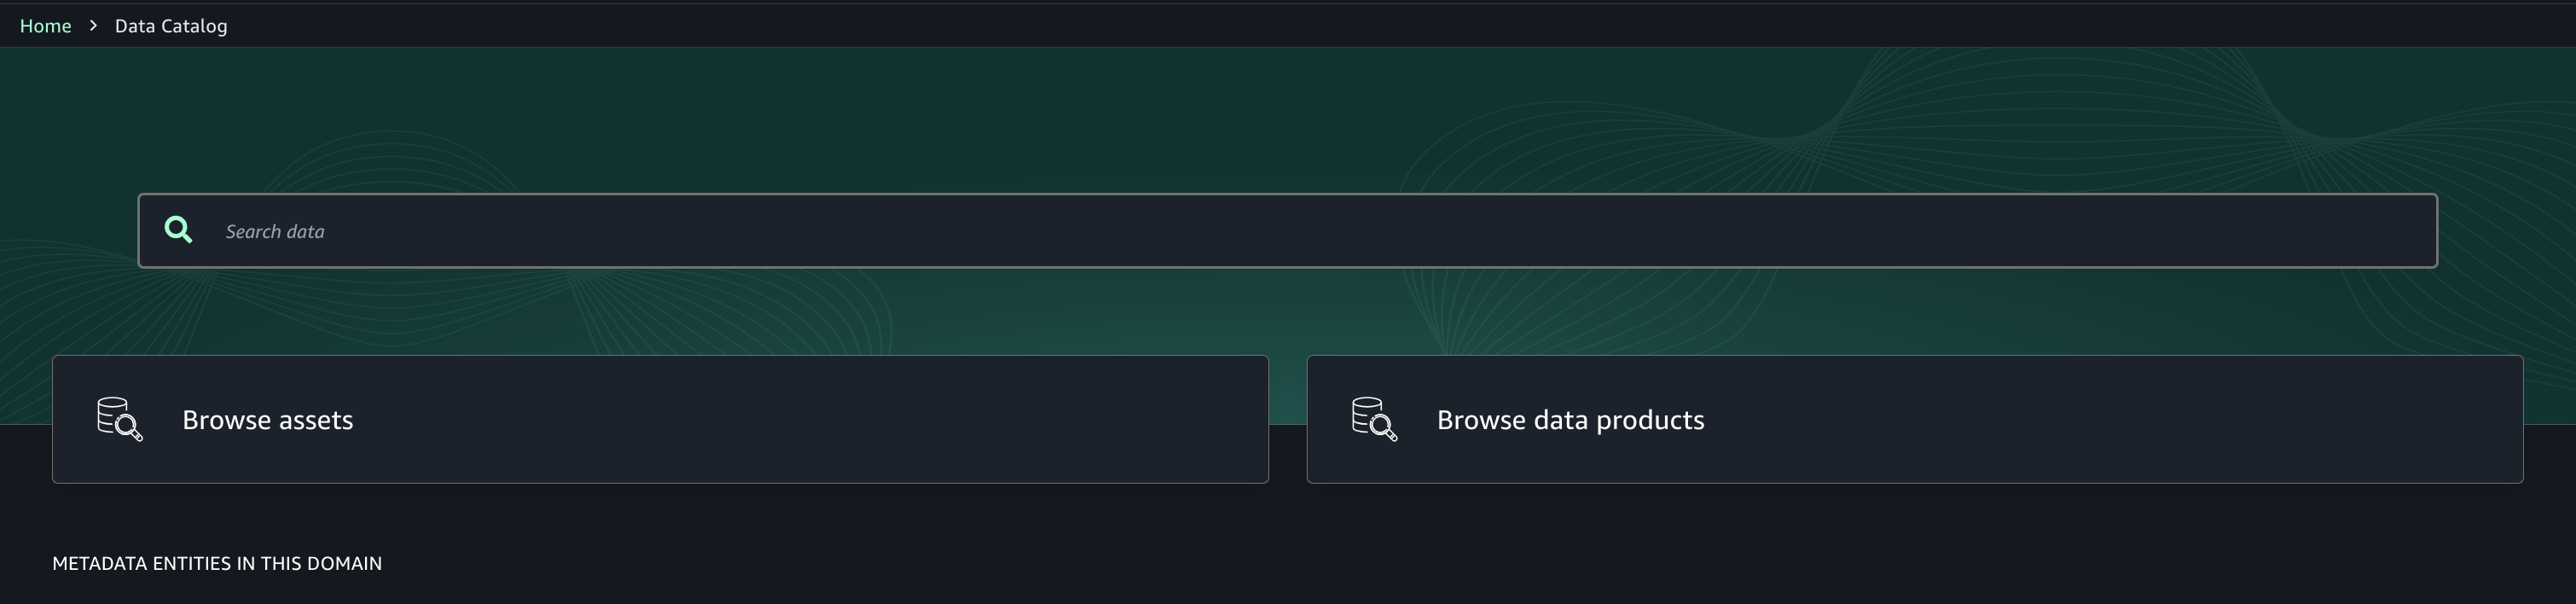
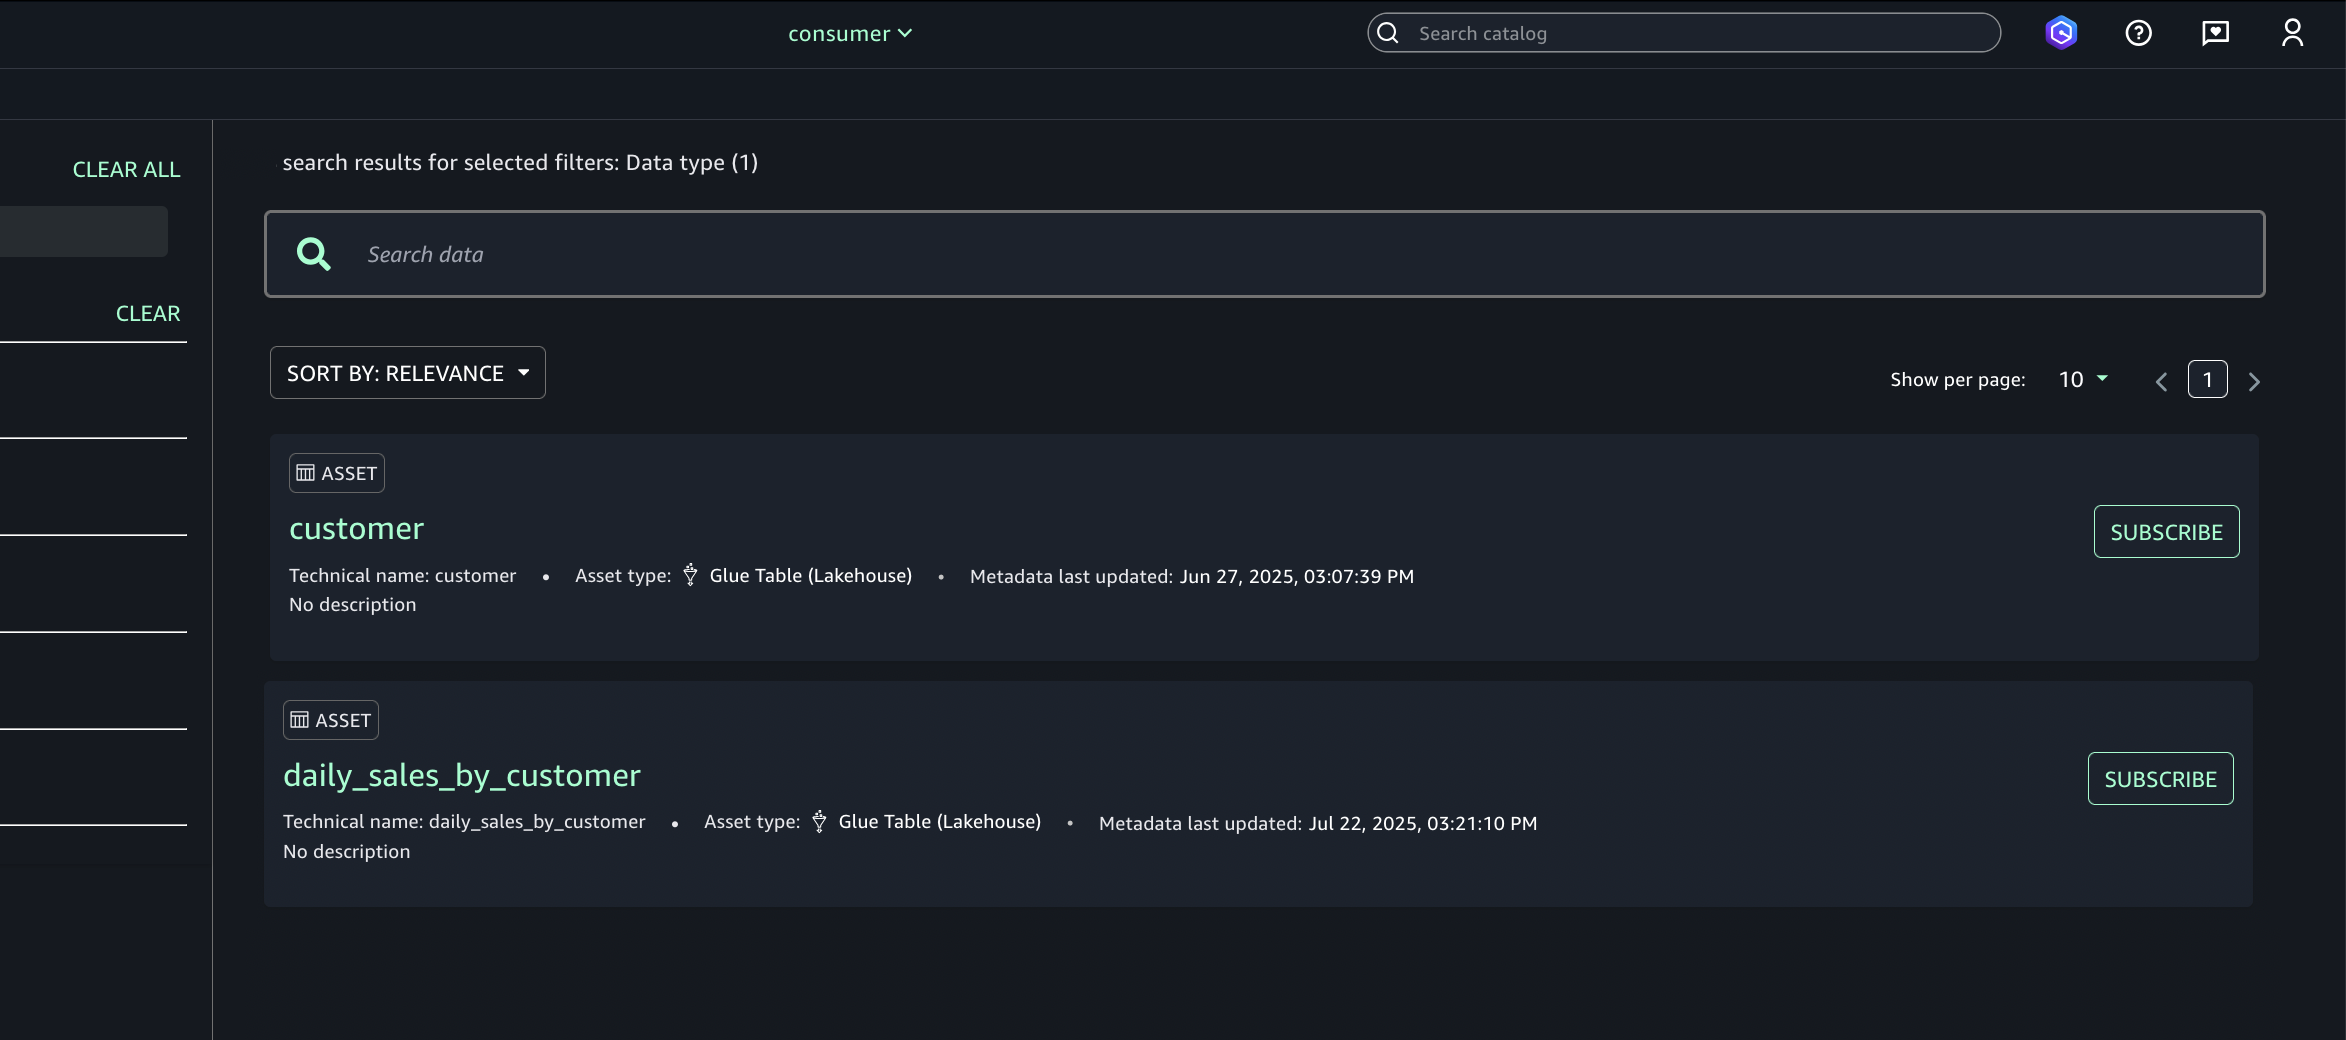
  3. Browse or search for the published asset (S3 tables from Account A).
  4. Select the desired asset (S3 tables from Account A) and choose Subscribe.
  5. In the subscription pop-up:
    1. Choose the target project for asset access.
    2. Provide a short justification for the access request.
  6. Submit the subscription request.
  7. Repeat step 6 to enable the consumer (Account C) teams to discover assets in Account B.

Approve or reject a subscription request

  1. In Account A, open the SageMaker Unified Studio portal.
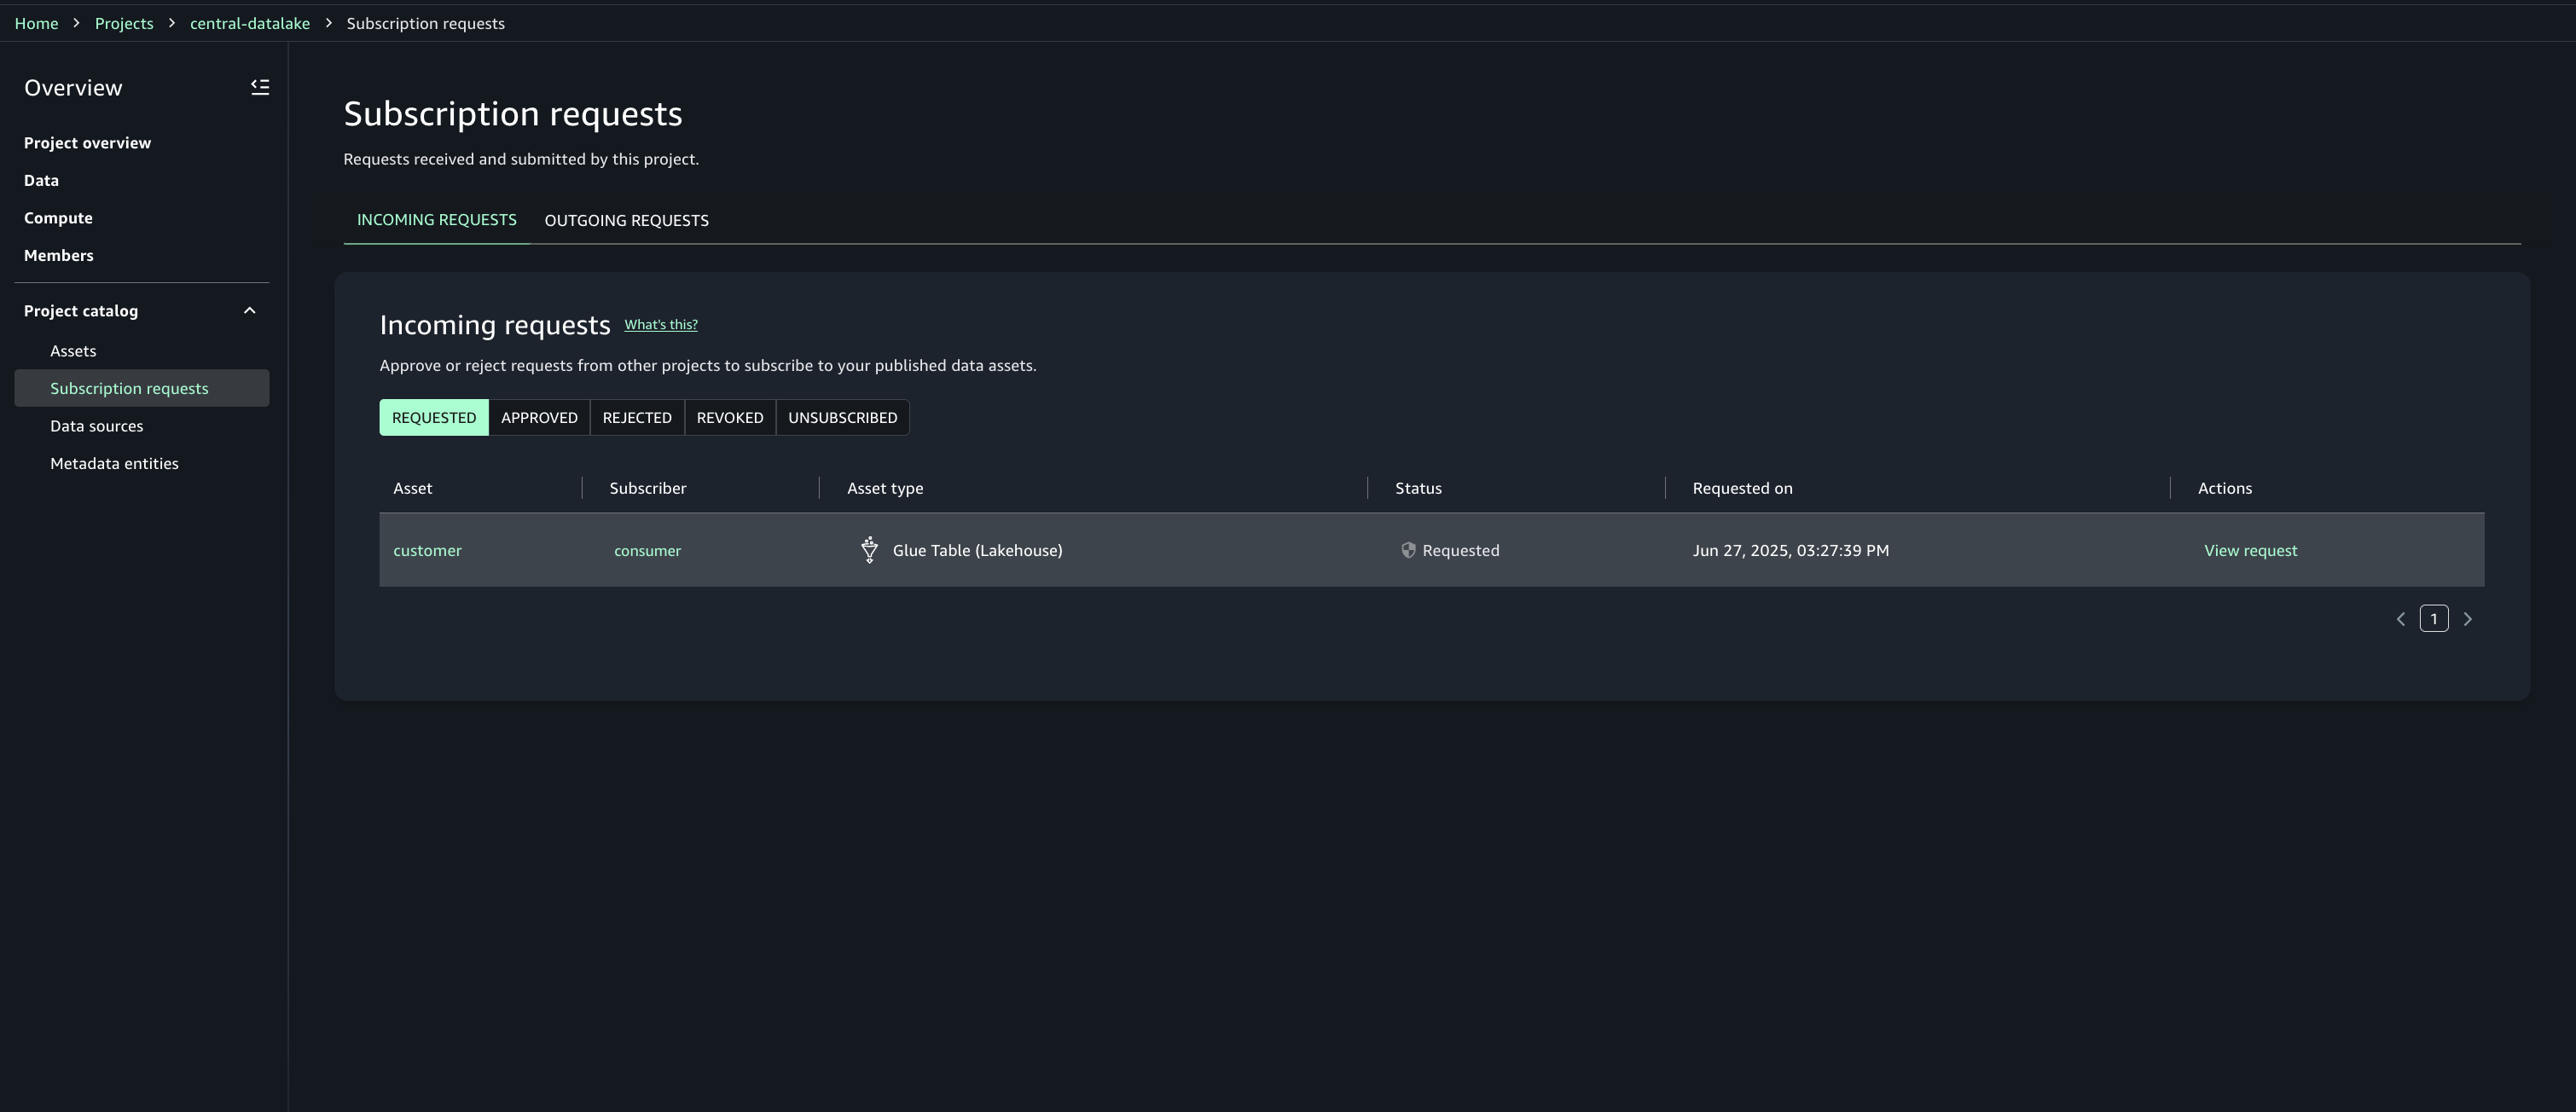
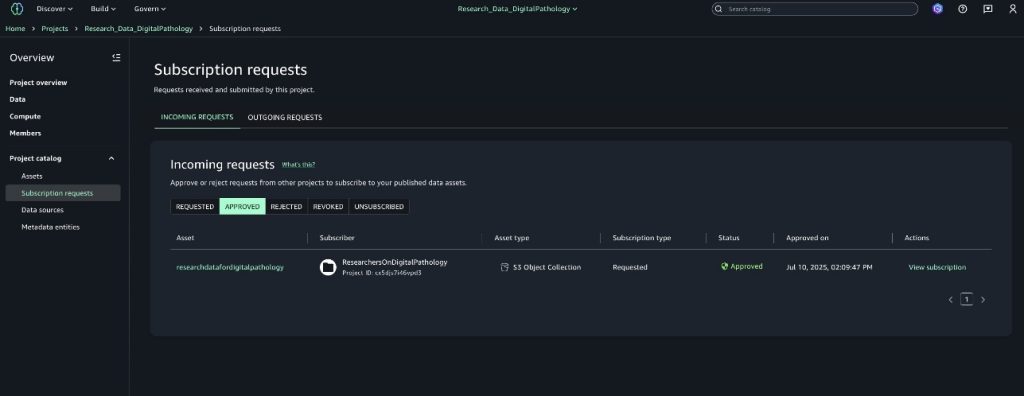
  2. Under Project catalog, Subscription requests, Incoming requests tab locate and view the subscription request.
  3. Review the requester and justification.
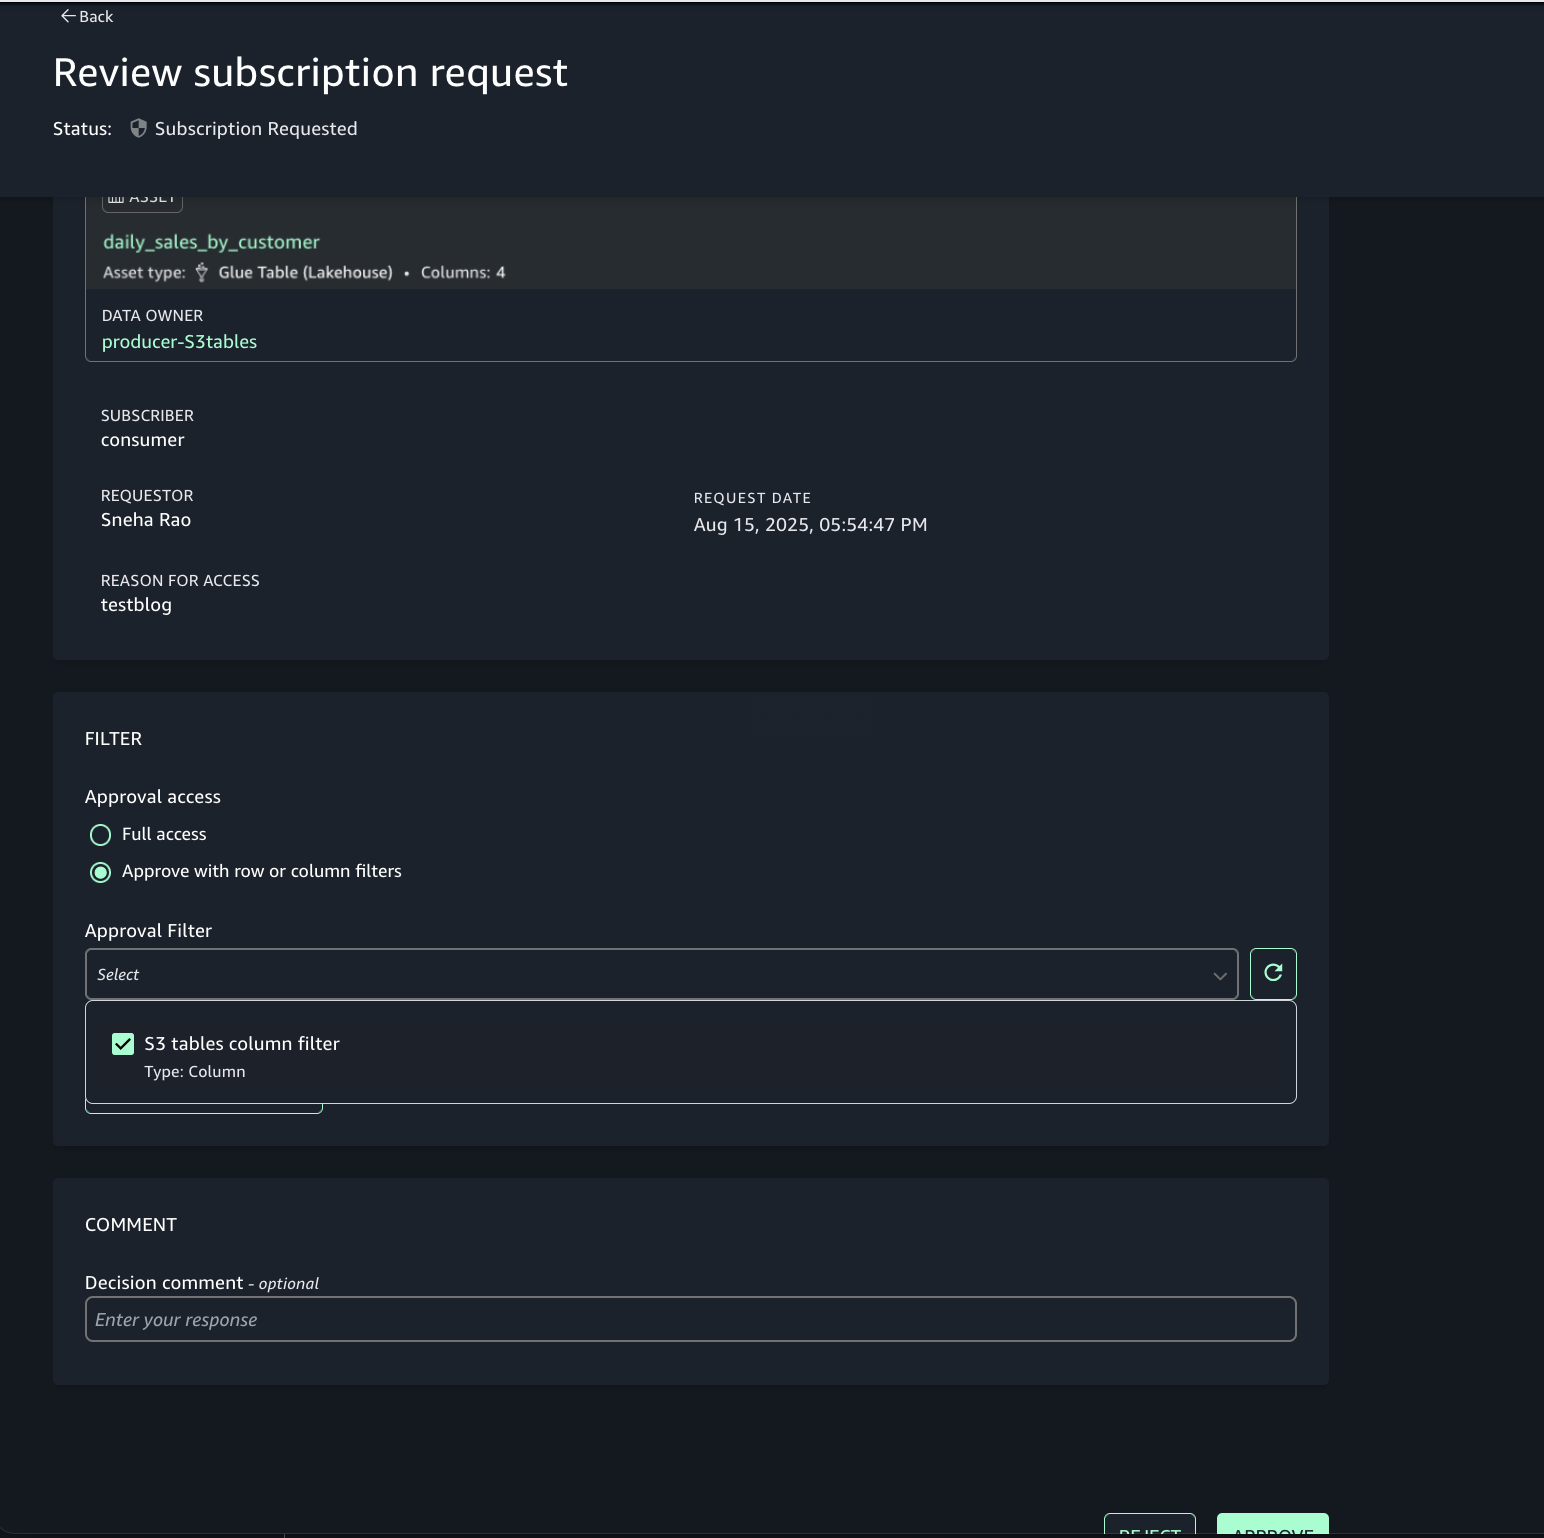
  4. Choose the option to approve with row and column filters. For this post, we use the filter that we created earlier.
  5. Repeat step 6 to enable the consumer (Account C) teams to discover assets in Account B.

Step 7: Analyze S3 table and S3 data together in query editor

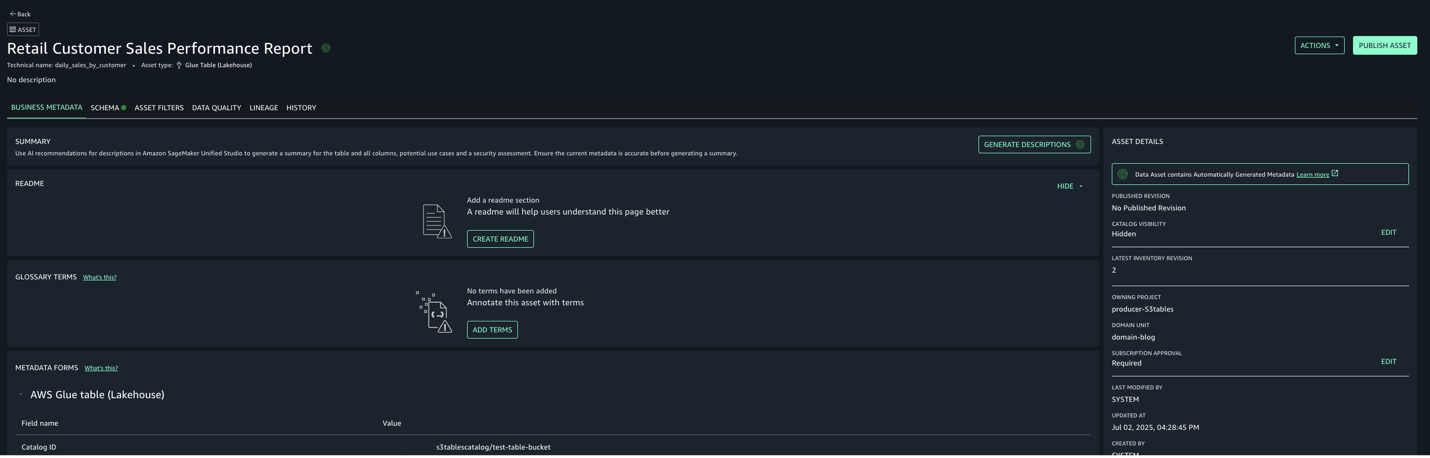
Account C (consumer) now has full access to the customer data in S3 from Account B, and the daily_sales_by_customer data in S3 tables from Account A with restricted columns. Both datasets contain a common column Customer_id.

To generate combined insights, assets from Account A and Account B can be queried and joined on Customer_id.

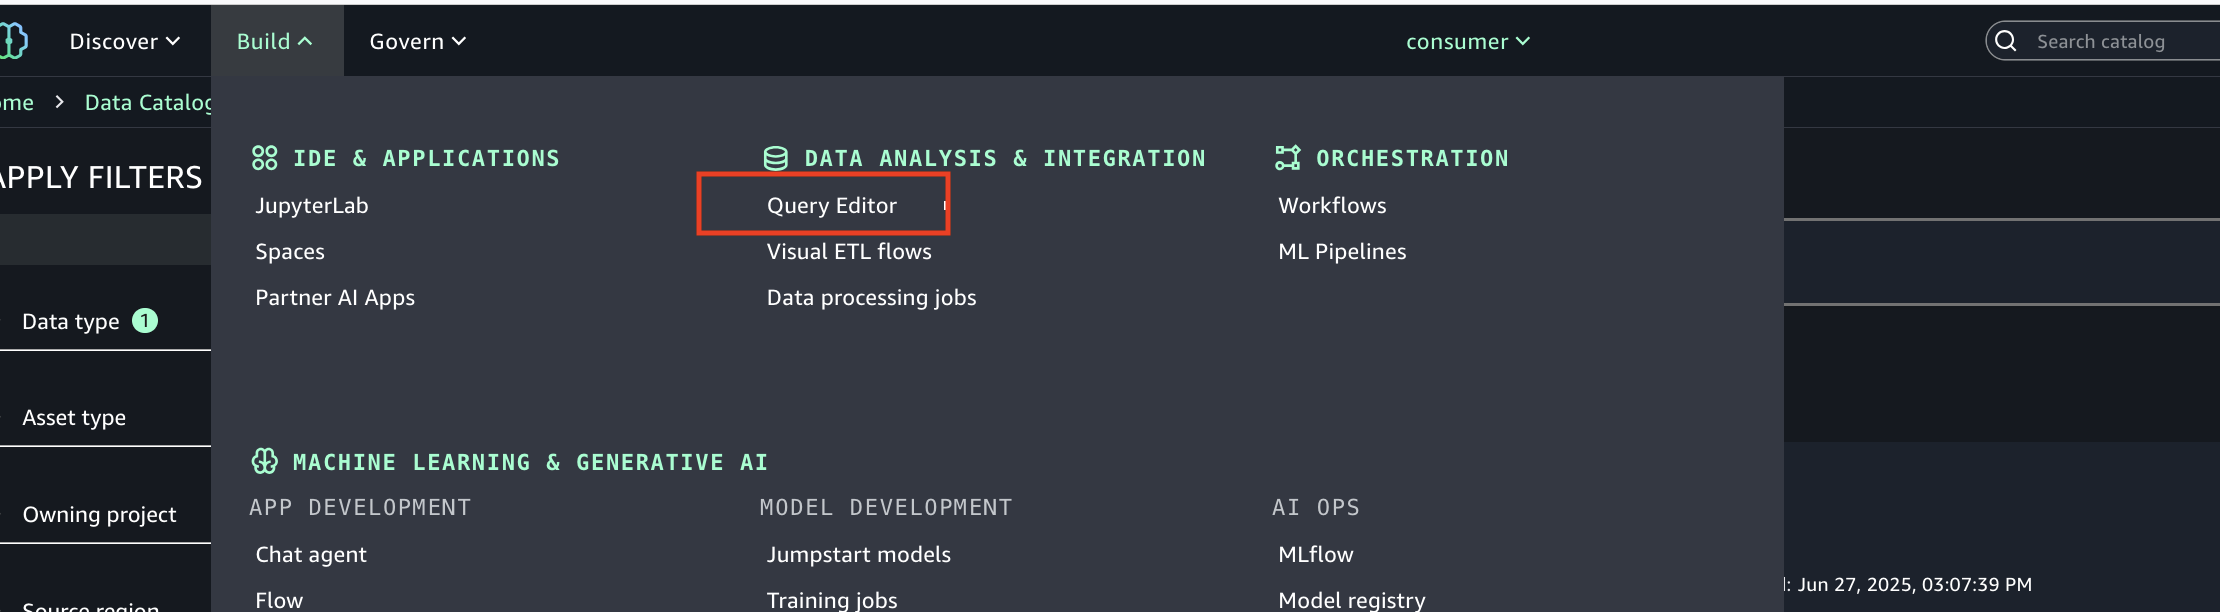
  1. In SageMaker Unified Studio (consumer project in Account C), go to the Build section and select Query Editor.
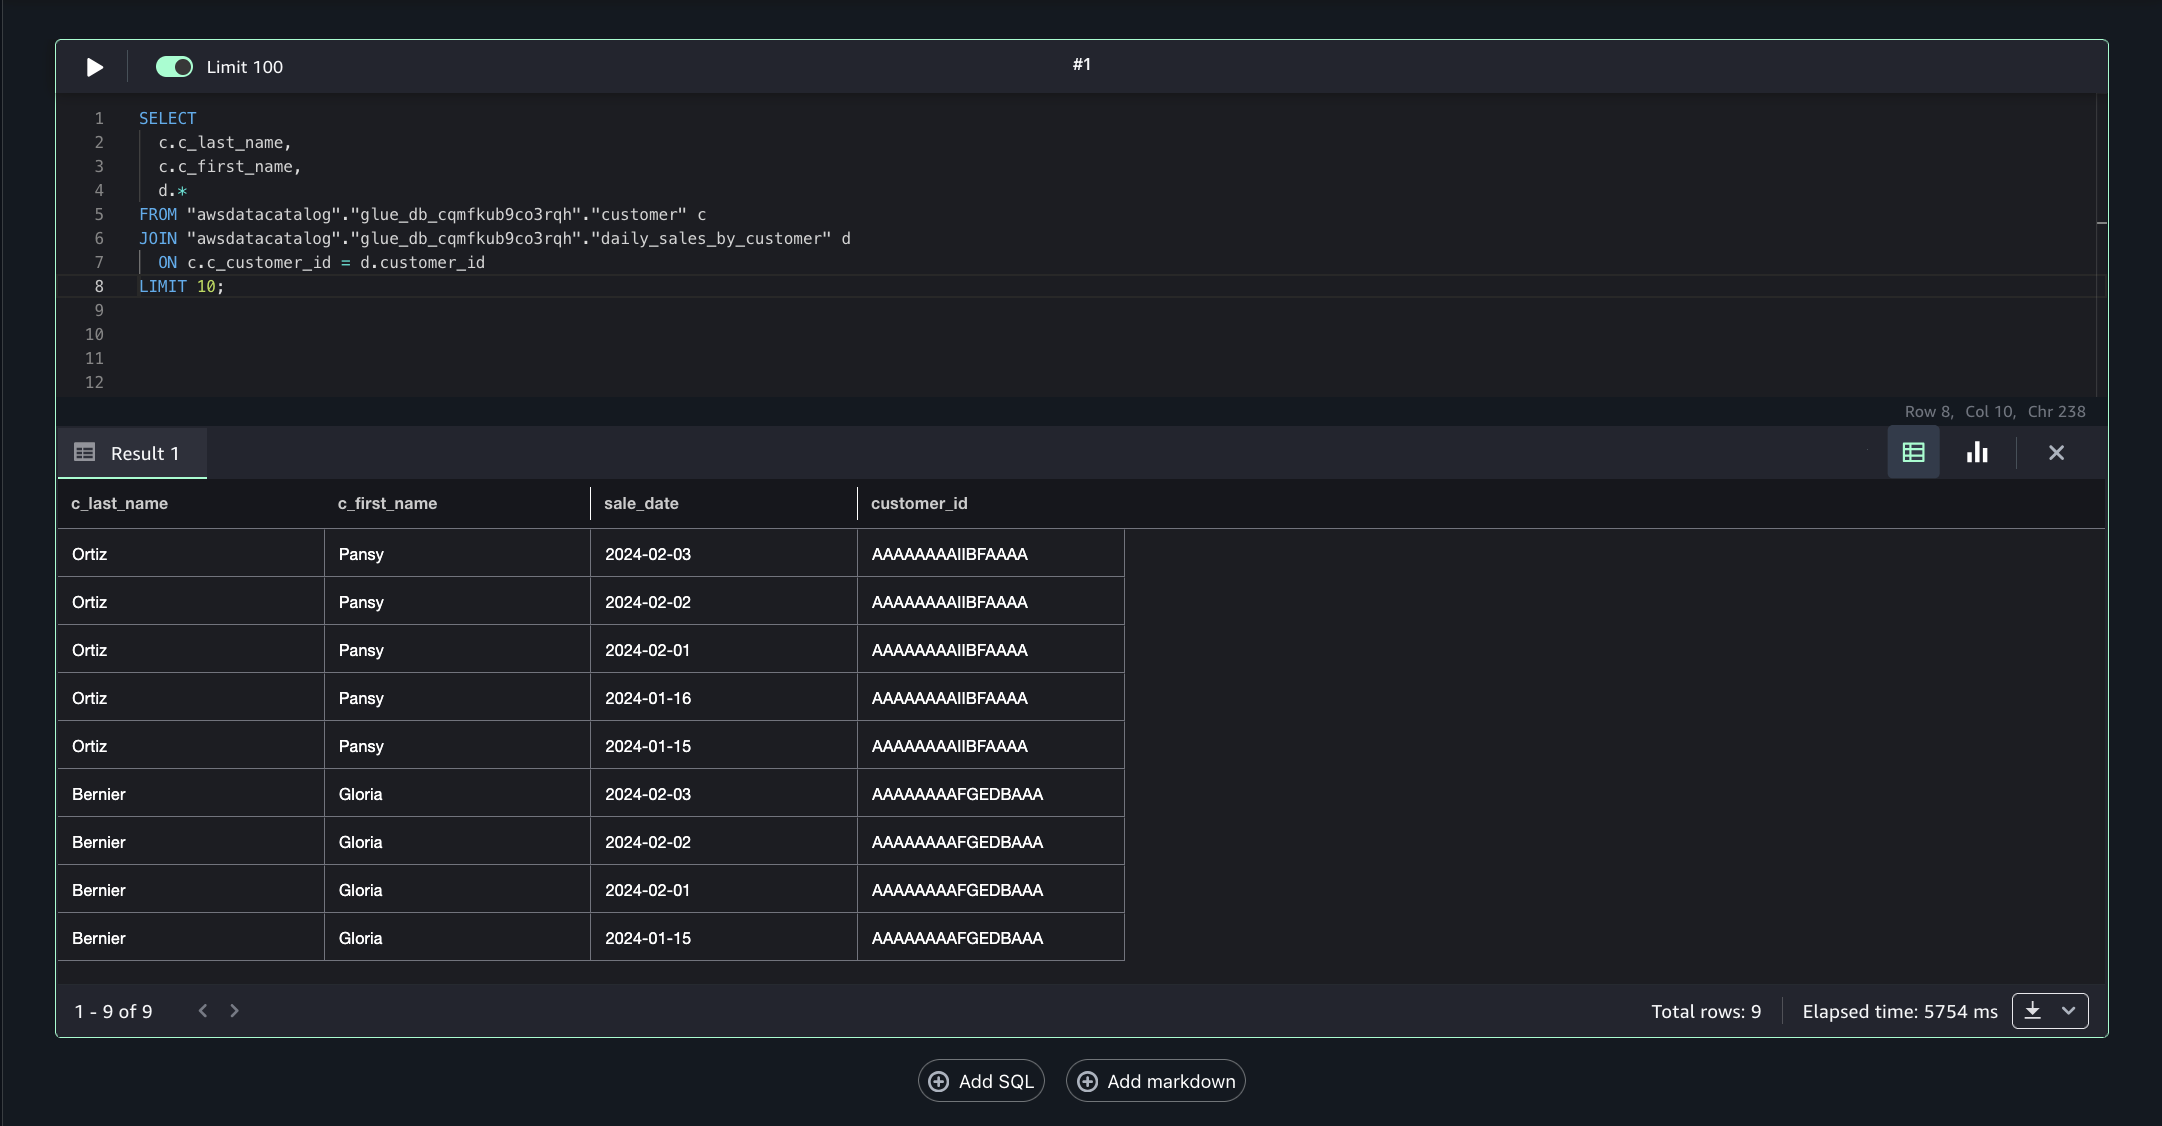
  2. Run the following SQL query to join the assets from Account B and Account A on the common column Customer_id, enabling unified cross-account analytics.
    SELECT
        c.c_last_name,
        c.c_first_name,
        d.*
    FROM "awsdatacatalog"."glue_db_cqmfkub9co3rqh"."customer" c
    JOIN "awsdatacatalog"."glue_db_cqmfkub9co3rqh"."daily_sales_by_customer" d
        ON c.c_customer_id = d.customer_id
    LIMIT 10;

This approach allows combining filtered, governed data from multiple accounts into a single query for comprehensive insights.

Clean up

To avoid ongoing charges, clean up the resources created during this walkthrough. Complete these steps in the specified order to facilitate proper resource deletion. You might need to add respective delete permissions for databases, table buckets, and tables if your IAM user or role doesn’t already have them.

  1. Delete any created IAM roles or policies.
  2. Delete all the projects you created in the SageMaker Unified Studio domain.
  3. Delete the SageMaker Unified Studio domain you created.

Conclusion

In this post, we explored how Amazon SageMaker Catalog integrates with S3 Tables to provide comprehensive data governance in cross-account environments. We demonstrated how data publishers can onboard S3 Tables to SageMaker Lakehouse while data consumers can efficiently search, request access, and leverage approved datasets for analytics and AI development.

The integration between SageMaker Catalog, S3 Tables, and AWS AWS Lake Formation creates a unified governance framework that eliminates data silos while maintaining robust security controls. Through automated subscription workflows and fine-grained access permissions, organizations can implement self-service data access without compromising compliance or data quality.


About the authors

Sneha Rao

Sneha Rao

Sneha is a Solutions Architect at AWS who helps strategic enterprise customers design architectures on the cloud. She’s passionate about creating inclusive learning experiences that make complex technologies approachable and impactful. Outside of work, Sneha enjoys painting, exploring local coffee shops, and going on outdoor adventures with her Cavapoo, Taz.

Deepmala Agarwal

Deepmala Agarwal

Deepmala is passionate about helping customers build out scalable, distributed, and data-driven solutions on AWS. When not at work, Deepmala likes spending time with family, walking, listening to music, watching movies, and cooking!

Viral Thakkar

Viral Thakkar

Viral is a Software Engineer at AWS, working on Amazon DataZone with a primary focus on distributed systems and data governance with deep expertise in building large-scale data analytics and pipelining solutions. He is passionate about tackling complex distributed systems challenges while also creating tools and automated scripts that simplify day-to-day workflows and improve productivity.

Santhosh Padmanabhan

Santhosh Padmanabhan

Santhosh is a Software Development Manager at AWS, leading the Amazon DataZone engineering team. His team designs, builds, and operates services specializing in data, machine learning, and AI governance. With deep expertise in building distributed data systems at scale, Santhosh plays a key role in advancing AWS’s data governance capabilities.

Abbas Makhdum

Abbas Makhdum

Abbas is Head of Product Marketing for Amazon SageMaker Catalog at AWS, where he leads go-to-market strategy and launches for data and AI governance solutions. With deep expertise across data, AI, and analytics, Abbas has also authored a book on data governance with O’Reilly. He is passionate about helping organizations unlock business value by making data and AI more accessible, transparent, and governed.

The Amazon SageMaker Lakehouse Architecture now supports Tag-Based Access Control for federated catalogs

Post Syndicated from Sandeep Adwankar original https://aws.amazon.com/blogs/big-data/the-amazon-sagemaker-lakehouse-architecture-now-supports-tag-based-access-control-for-federated-catalogs/

The Amazon SageMaker lakehouse architecture has expanded its tag-based access control (TBAC) capabilities to include federated catalogs. This enhancement extends beyond the default AWS Glue Data Catalog resources to encompass Amazon S3 Tables, Amazon Redshift data warehouses. TBAC is also supported on federated catalogs from data sources Amazon DynamoDB, MySQL, PostgreSQL, SQL Server, Oracle, Amazon DocumentDB, Google BigQuery, and Snowflake. TBAC provides you a sophisticated permission management that uses tags to create logical groupings of catalog resources, enabling administrators to implement fine-grained access controls across their entire data landscape without managing individual resource-level permissions.

Traditional data access management often requires manual assignment of permissions at the resource level, creating significant administrative overhead. TBAC solves this by introducing an automated, inheritance-based permission model. When administrators apply tags to data resources, access permissions are automatically inherited, eliminating the need for manual policy modifications when new tables are added. This streamlined approach not only reduces administrative burden but also enhances security consistency across the data ecosystem.

TBAC can be set up through the AWS Lake Formation console, and accessible using Amazon Redshift, Amazon Athena, Amazon EMR, AWS Glue, and Amazon SageMaker Unified Studio. This makes it valuable for organizations managing complex data landscapes with multiple data sources and large datasets. TBAC is especially beneficial for enterprises implementing data mesh architectures, maintaining regulatory compliance, or scaling their data operations across multiple departments. Furthermore, TBAC enables efficient data sharing across different accounts, making it easier to maintain secure collaboration.

In this post, we illustrate how to get started with fine-grained access control of S3 Tables and Redshift tables in the lakehouse using TBAC. We also show how to access these lakehouse tables using your choice of analytics services, such as Athena, Redshift, and Apache Spark in Amazon EMR Serverless in Amazon SageMaker Unified Studio.

Solution overview

For illustration, we consider a fictional company called Example Retail Corp, as covered in the blog post Accelerate your analytics with Amazon S3 Tables and Amazon SageMaker Lakehouse. Example Retail’s leadership has decided to use the SageMaker lakehouse architecture to unify data across S3 Tables and their Redshift data warehouse. With this lakehouse architecture, they can now conduct analyses across their data to identify at-risk customers, understand the impact of personalized marketing campaigns on customer churn, and develop targeted retention and sales strategies.

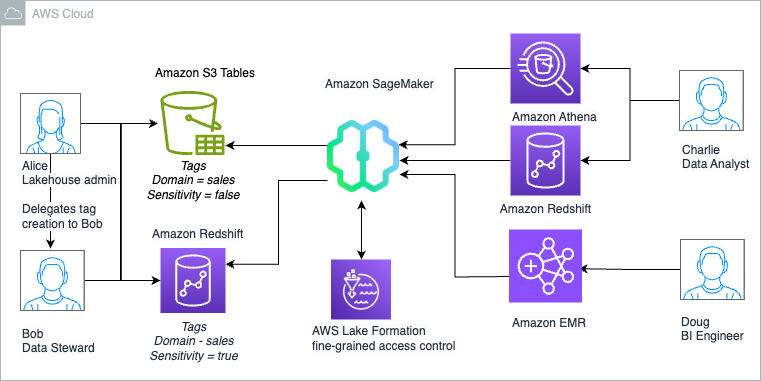
Alice is a data administrator with the AWS Identity and Access Management (IAM) role LHAdmin in Example Retail Corp, and she wants to implement tag-based access control to scale permissions across their data lake and data warehouse resources. She is using S3 Tables with Iceberg transactional capability to achieve scalability as updates are streamed across billions of customer interactions, while providing the same durability, availability, and performance characteristics that S3 is known for. She already has a Redshift namespace, which contains historical and current data about sales, customers prospects, and churn information. Alice supports an extended team of developers, engineers, and data scientists who require access to the data environment to develop business insights, dashboards, ML models, and knowledge bases. This team includes:

  • Bob, a data steward with IAM role DataSteward, is the domain owner and manages access to the S3 Tables and warehouse data. He enables other teams who build reports to be shared with leadership.
  • Charlie, a data analyst with IAM role DataAnalyst, builds ML forecasting models for sales growth using the pipeline or customer conversion across multiple touchpoints, and makes those available to finance and planning teams.
  • Doug, a BI engineer with IAM role BIEngineer, builds interactive dashboards to funnel customer prospects and their conversions across multiple touchpoints, and makes those available to thousands of sales team members.

Alice decides to use the SageMaker lakehouse architecture to unify data across S3 Tables and Redshift data warehouse. Bob can now bring his domain data into one place and manage access to multiple teams requesting access to his data. Charlie can quickly build Amazon QuickSight dashboards and use his Redshift and Athena expertise to provide quick query results. Doug can build Spark-based processing with AWS Glue or Amazon EMR to build ML forecasting models.

Alice’s goal is to use TBAC to make fine-grained access much more scalable, because they can grant permissions on many resources at once and permissions are updated accordingly when tags for resources are added, changed, or removed.The following diagram illustrates the solution architecture.

Alice as Lakehouse admin and Bob as Data Steward determines that following high-level steps are needed to deploy the solution:

  1. Create an S3 Tables bucket and enable integration with the Data Catalog. This will make the resources available under the federated catalog s3tablescatalog in the lakehouse architecture with Lake Formation for access control. Create a namespace and a table under the table bucket where the data will be stored.
  2. Create a Redshift cluster with tables, publish your data warehouse to the Data Catalog, and create a catalog registering the namespace. This will make the resources available under a federated catalog in the lakehouse architecture with Lake Formation for access control.
  3. Delegate permissions to create tags and grant permissions on Data Catalog resources to DataSteward.
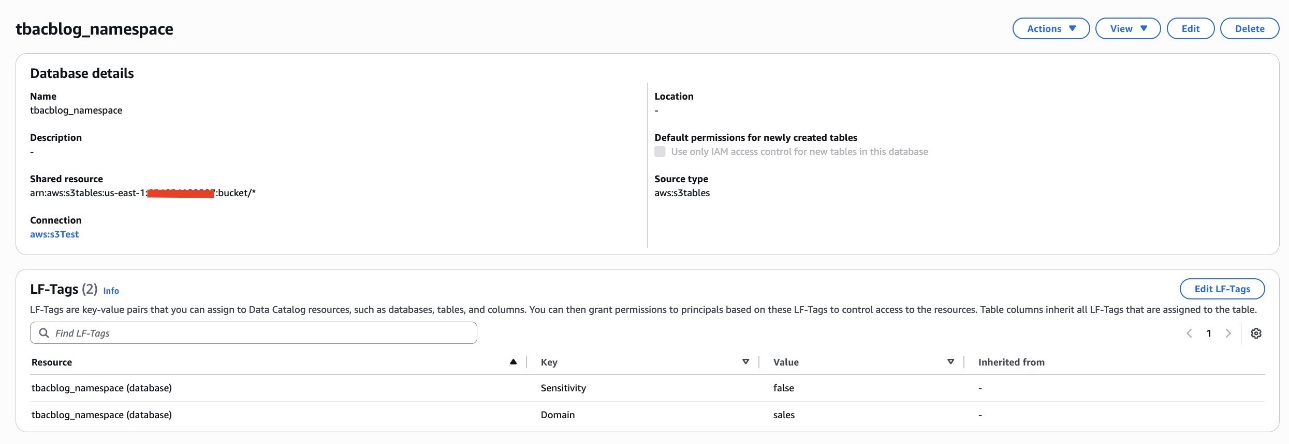
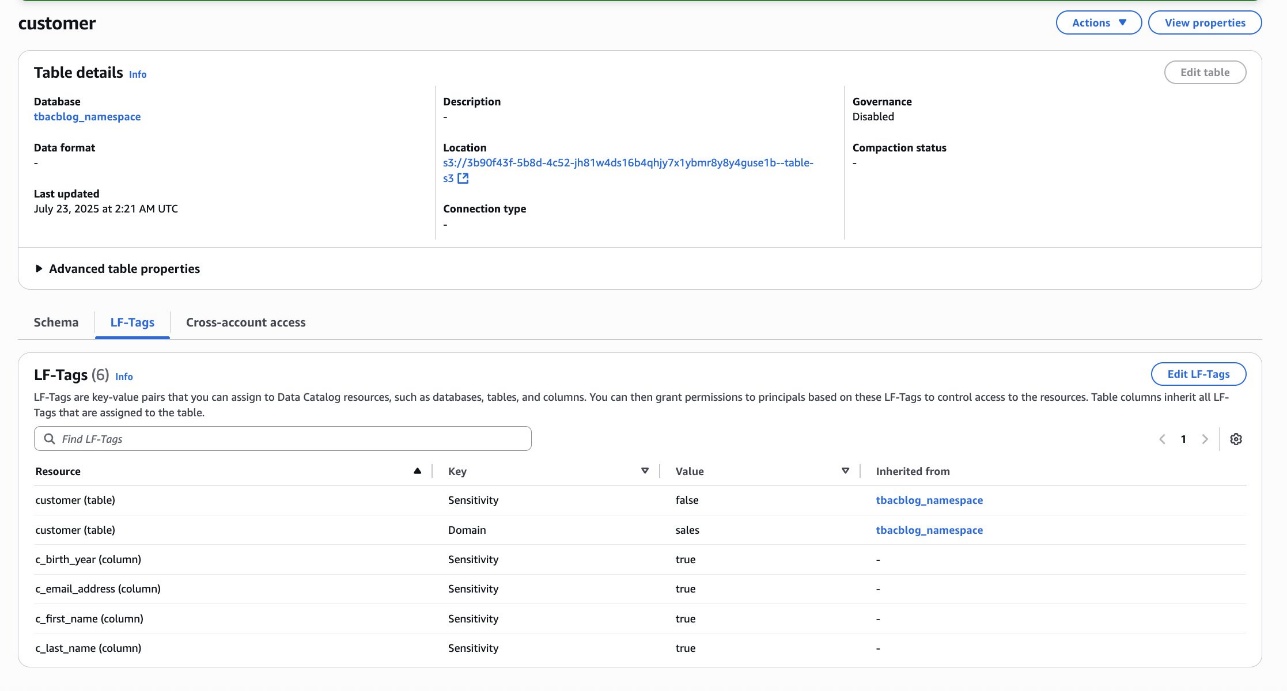
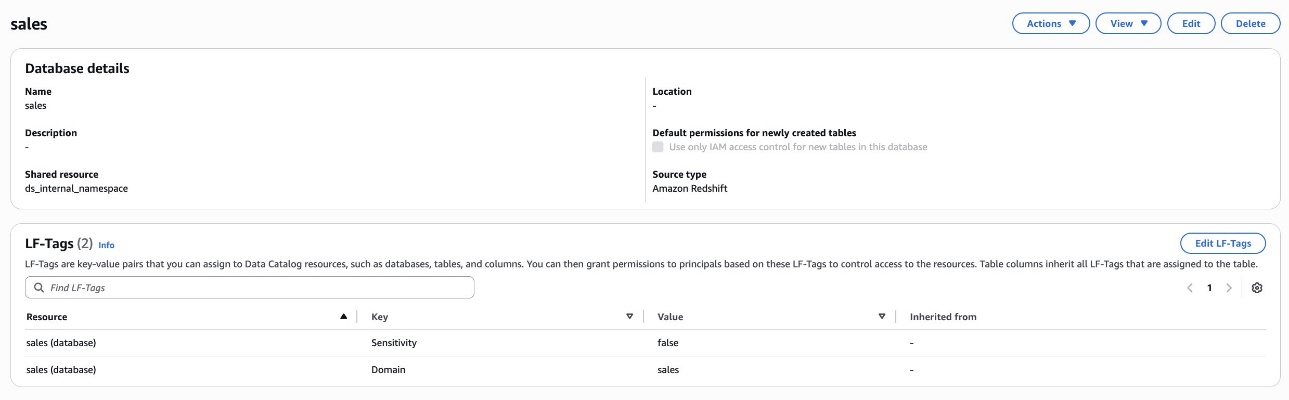
  4. As DataSteward, define tag ontology based on the use case and create Tags. Assign these LF-Tags to the resources (database or table) to logically group lakehouse resources for sharing based on access patterns.
  5. Share the S3 Tables catalog table and Redshift table using tag-based access control to DataAnalyst, who uses Athena for analysis and Redshift Spectrum for generating the report.
  6. Share the S3 Tables catalog table and Redshift table using tag-based access control to BIEngineer, who uses Spark in EMR Serverless to further process the datasets.

Data steward defines the tags and assignment to resources as shown:

Tags Data Resources

Domain = sales

Sensitivity = false

S3 Table:

customer(

c_salutation,              c_preferred_cust_flag,c_first_sales_date_sk,
c_customer_sk ,
c_login ,
c_current_cdemo_sk ,
c_current_hdemo_sk ,
c_current_addr_sk ,
c_customer_id ,
c_last_review_date_sk ,
c_birth_month ,
c_birth_country ,
c_birth_day ,
c_first_shipto_date_sk
)

Domain = sales

Sensitivity = true

S3 Table:

customer(

c_first_name,

c_last_name,

c_email_address,

c_birth_year)

Domain = sales

Sensitivity = false

Redshift Table:

sales.store_sales

The following table summarizes the tag expression that is granted to roles for resource access:

User Persona Permission Granted Access
Bob DataSteward SUPER_USER on catalogs Admin access on customer and store_sales.
Charlie DataAnalyst

Domain = sales

Sensitivity = false

Access to non -sensitive data that is aligned to sales domain: customer(non-sensitive columns) and store_sales.
Doug BIEngineer Domain = sales Access to all datasets that is aligned to sales domain: customer and store_sales.

Prerequisites

To follow along with this post, complete the following prerequisite steps:

  1. Have an AWS account and admin user with access to the following AWS services:
    1. Athena
    2. Amazon EMR
    3. IAM
    4. Lake Formation and the Data Catalog
    5. Amazon Redshift
    6. Amazon S3
    7. IAM Identity Center
    8. Amazon SageMaker Unified Studio
  2. Create a data lake admin (LHAdmin). For instructions, see Create a data lake administrator.
  3. Create an IAM role named DataSteward and attach permissions for AWS Glue and Lake Formation access. For instructions, refer to Data lake administrator permissions.
  4. Create an IAM role named DataAnalyst and attach permissions for Amazon Redshift and Athena access. For instructions, refer to Data analyst permissions.
  5. Create an IAM role named BIEngineer and attach permissions for Amazon EMR access. This is also the EMR runtime role that the Spark job will use to access the tables. For instructions on the role permissions, refer to Job runtime roles for EMR serverless.
  6. Create an IAM role named RedshiftS3DataTransferRole following the instructions in Prerequisites for managing Amazon Redshift namespaces in the AWS Glue Data Catalog.
  7. Create an EMR Studio and attach an EMR Serverless namespace in a private subnet to it, following the instructions in Run interactive workloads on Amazon EMR Serverless from Amazon EMR Studio.

Create data lake tables using an S3 Tables bucket and integrate with the lakehouse architecture

Alice completes the following steps to create a table bucket and enable integration with analytics services:

  1. Sign in to the Amazon S3 console as LHAdmin.
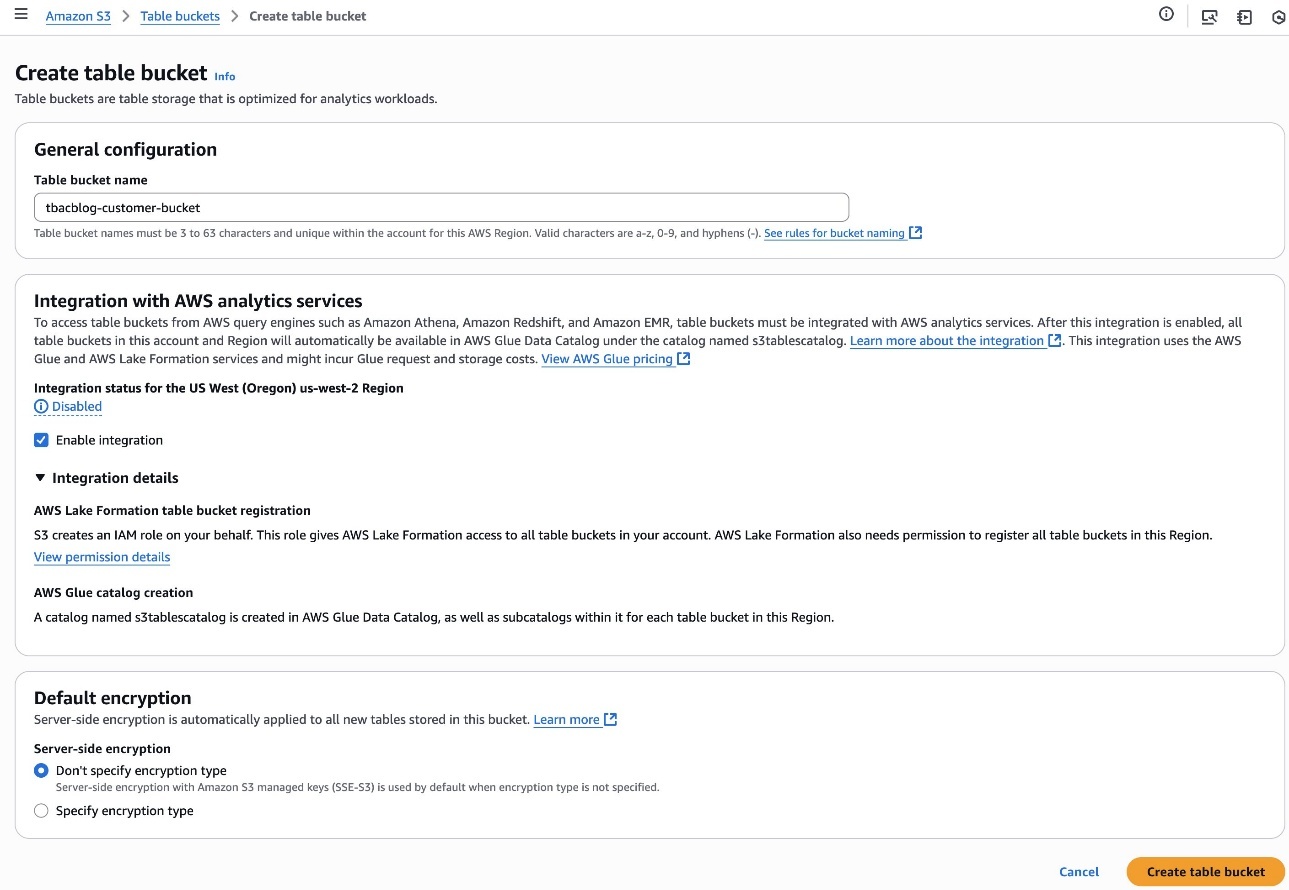
  2. Choose Table buckets in the navigation pane and create a table bucket.
  3. For Table bucket name, enter a name, such as tbacblog-customer-bucket.
  4. For Integration with AWS analytics services, choose Enable integration.
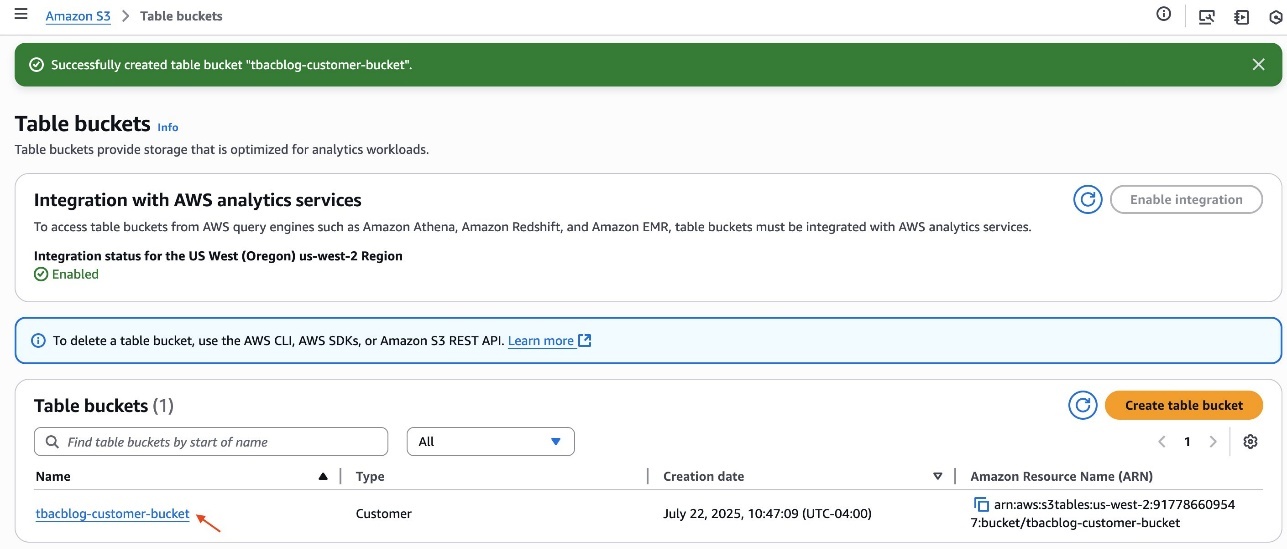
  5. Choose Create table bucket.
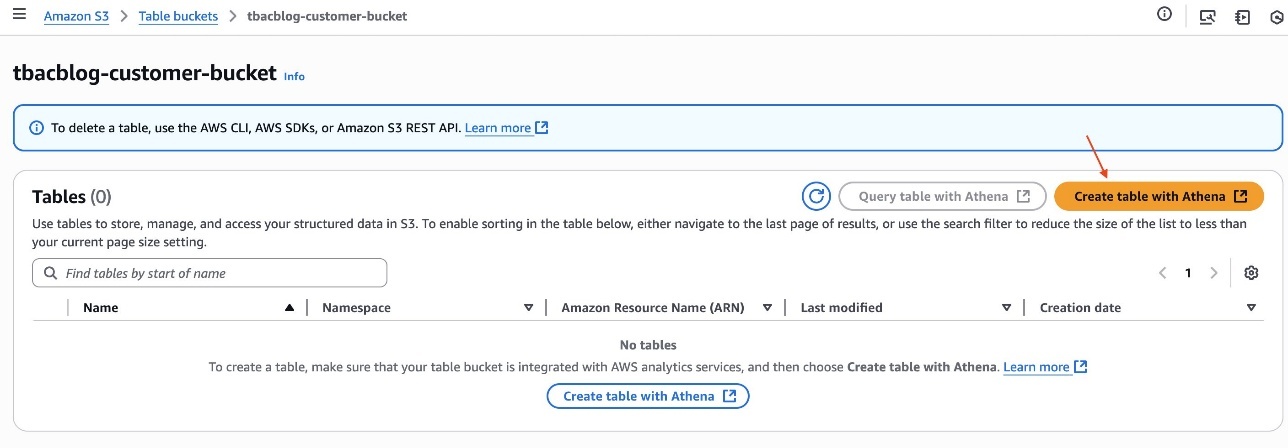
  6. After you create the table, click the hyperlink of the table bucket name.
  7. Choose Create table with Athena.
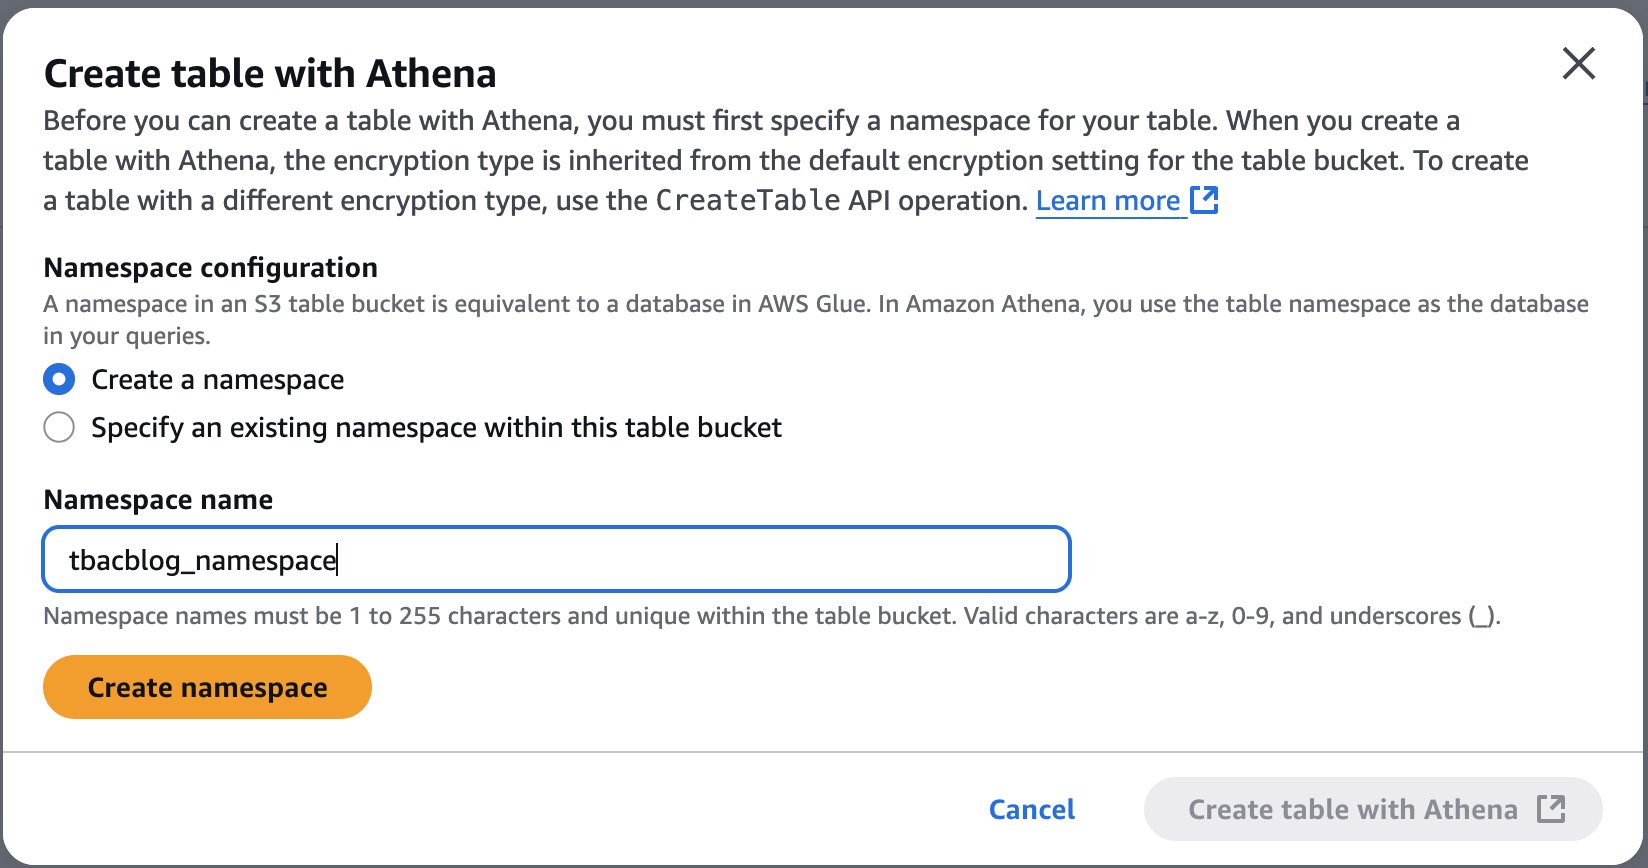
  8. Create a namespace and provide a namespace name. For example, tbacblog_namespace.
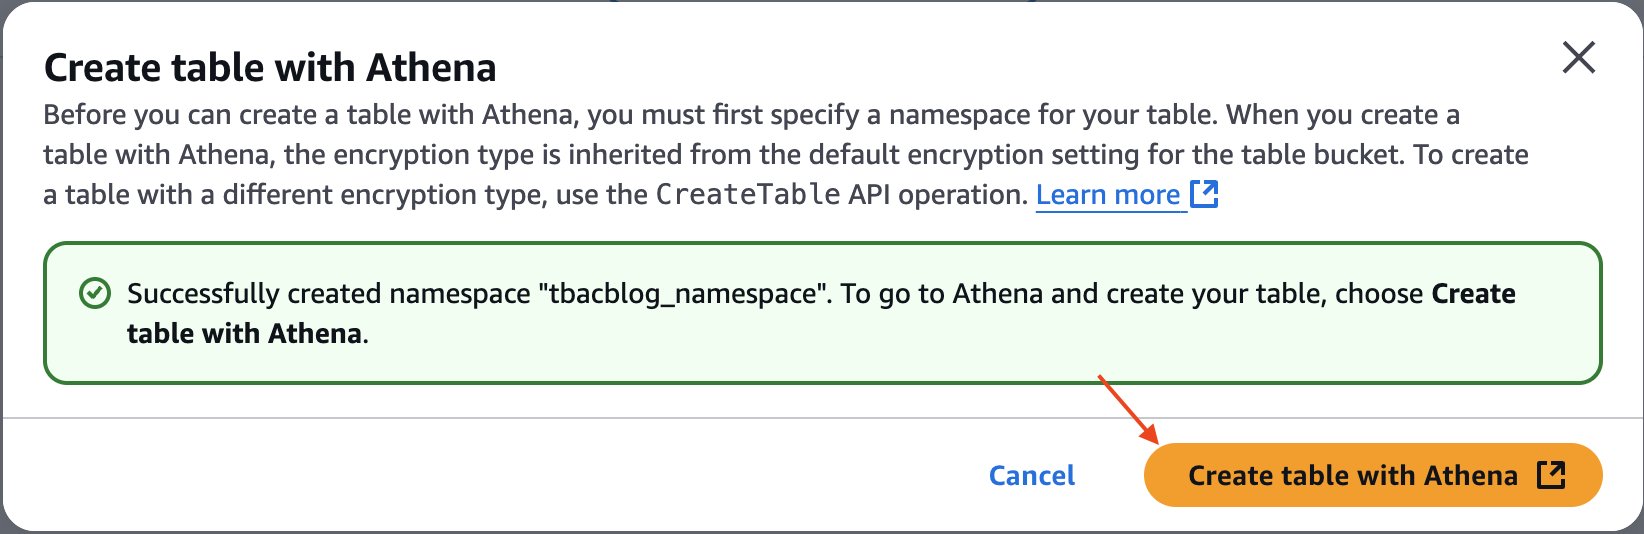
  9. Choose Create namespace.
  10. Now proceed to creating table schema and populating it by choosing Create table with Athena.
  11. On the Athena console, run the following SQL script to create a table:
    CREATE TABLE `tbacblog_namespace`.customer (
      c_salutation string, 
      c_preferred_cust_flag string, 
      c_first_sales_date_sk int, 
      c_customer_sk int, 
      c_login string, 
      c_current_cdemo_sk int, 
      c_first_name string, 
      c_current_hdemo_sk int, 
      c_current_addr_sk int, 
      c_last_name string, 
      c_customer_id string, 
      c_last_review_date_sk int, 
      c_birth_month int, 
      c_birth_country string, 
      c_birth_year int, 
      c_birth_day int, 
      c_first_shipto_date_sk int, 
      c_email_address string)
    TBLPROPERTIES ('table_type' = 'iceberg');
    
    
    INSERT INTO tbacblog_namespace.customer
    VALUES('Dr.','N',2452077,13251813,'Y',1381546,'Joyce',2645,2255449,'Deaton','AAAAAAAAFOEDKMAA',2452543,1,'GREECE',1987,29,2250667,'[email protected]'),
    ('Dr.','N',2450637,12755125,'Y',1581546,'Daniel',9745,4922716,'Dow','AAAAAAAAFLAKCMAA',2432545,1,'INDIA',1952,3,2450667,'[email protected]'),
    ('Dr.','N',2452342,26009249,'Y',1581536,'Marie',8734,1331639,'Lange','AAAAAAAABKONMIBA',2455549,1,'CANADA',1934,5,2472372,'[email protected]'),
    ('Dr.','N',2452342,3270685,'Y',1827661,'Wesley',1548,11108235,'Harris','AAAAAAAANBIOBDAA',2452548,1,'ROME',1986,13,2450667,'[email protected]'),
    ('Dr.','N',2452342,29033279,'Y',1581536,'Alexandar',8262,8059919,'Salyer','AAAAAAAAPDDALLBA',2952543,1,'SWISS',1980,6,2650667,'[email protected]'),
    ('Miss','N',2452342,6520539,'Y',3581536,'Jerry',1874,36370,'Tracy','AAAAAAAALNOHDGAA',2452385,1,'ITALY',1957,8,2450667,'[email protected]');
    
    SELECT * FROM tbacblog_namespace.customer;

You have now created the S3 Tables table customer, populated it with data, and integrated it with the lakehouse architecture.

Set up data warehouse tables using Amazon Redshift and integrate them with the lakehouse architecture

In this section, Alice sets up data warehouse tables using Amazon Redshift and integrates them with the lakehouse architecture.

Create a Redshift cluster and publish it to the Data Catalog

Alice completes the following steps to create a Redshift cluster and publish it to the Data Catalog:

  1. Create a Redshift Serverless namespace called salescluster. For instructions, refer to Get started with Amazon Redshift Serverless data warehouses.
  2. Sign in to the Redshift endpoint salescluster as an admin user.
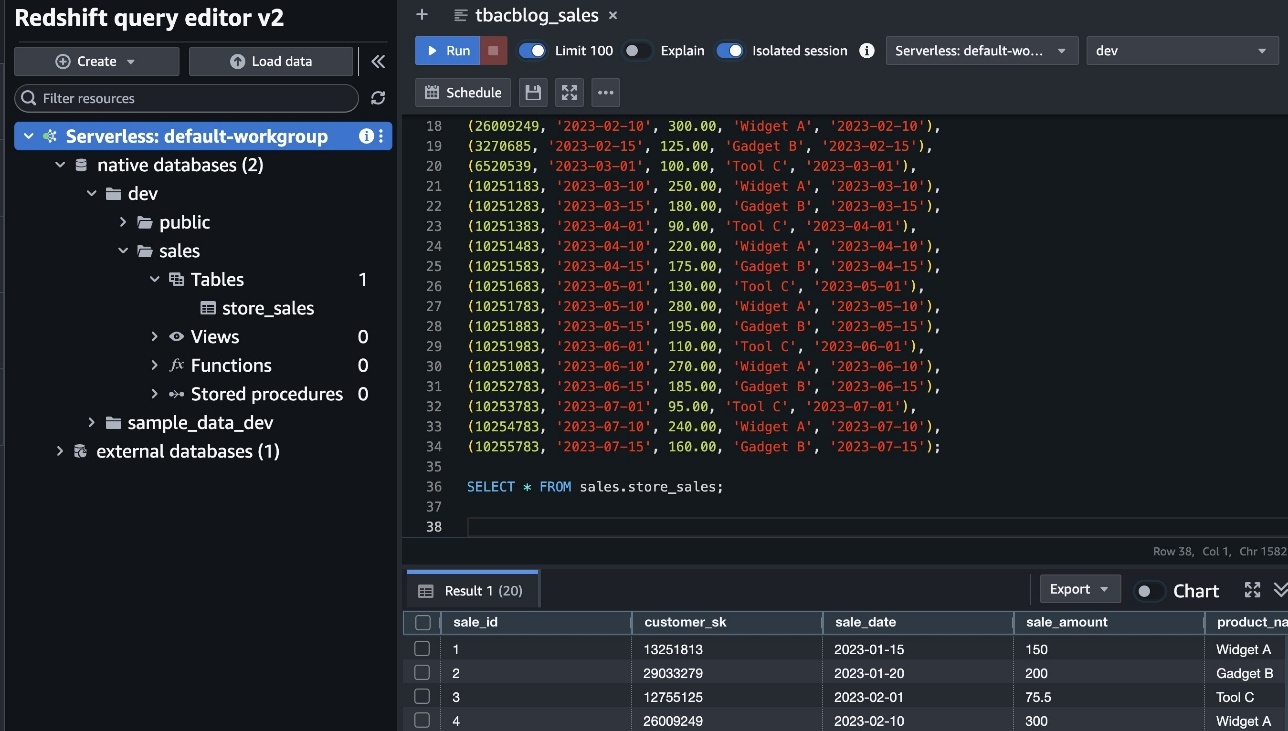
  3. Run the following script to create a table under the dev database under the public schema:
    CREATE SCHEMA sales;
    CREATE TABLE sales.store_sales (
    sale_id INTEGER IDENTITY(1,1) PRIMARY KEY,
    customer_sk INTEGER NOT NULL,
    sale_date DATE NOT NULL,
    sale_amount DECIMAL(10, 2) NOT NULL,
    product_name VARCHAR(100) NOT NULL,
    last_purchase_date DATE
    );
    
    INSERT INTO sales.store_sales (customer_sk, sale_date, sale_amount, product_name, last_purchase_date)
    VALUES
    (13251813, '2023-01-15', 150.00, 'Widget A', '2023-01-15'),
    (29033279, '2023-01-20', 200.00, 'Gadget B', '2023-01-20'),
    (12755125, '2023-02-01', 75.50, 'Tool C', '2023-02-01'),
    (26009249, '2023-02-10', 300.00, 'Widget A', '2023-02-10'),
    (3270685, '2023-02-15', 125.00, 'Gadget B', '2023-02-15'),
    (6520539, '2023-03-01', 100.00, 'Tool C', '2023-03-01'),
    (10251183, '2023-03-10', 250.00, 'Widget A', '2023-03-10'),
    (10251283, '2023-03-15', 180.00, 'Gadget B', '2023-03-15'),
    (10251383, '2023-04-01', 90.00, 'Tool C', '2023-04-01'),
    (10251483, '2023-04-10', 220.00, 'Widget A', '2023-04-10'),
    (10251583, '2023-04-15', 175.00, 'Gadget B', '2023-04-15'),
    (10251683, '2023-05-01', 130.00, 'Tool C', '2023-05-01'),
    (10251783, '2023-05-10', 280.00, 'Widget A', '2023-05-10'),
    (10251883, '2023-05-15', 195.00, 'Gadget B', '2023-05-15'),
    (10251983, '2023-06-01', 110.00, 'Tool C', '2023-06-01'),
    (10251083, '2023-06-10', 270.00, 'Widget A', '2023-06-10'),
    (10252783, '2023-06-15', 185.00, 'Gadget B', '2023-06-15'),
    (10253783, '2023-07-01', 95.00, 'Tool C', '2023-07-01'),
    (10254783, '2023-07-10', 240.00, 'Widget A', '2023-07-10'),
    (10255783, '2023-07-15', 160.00, 'Gadget B', '2023-07-15');
    
    SELECT * FROM sales.store_sales;

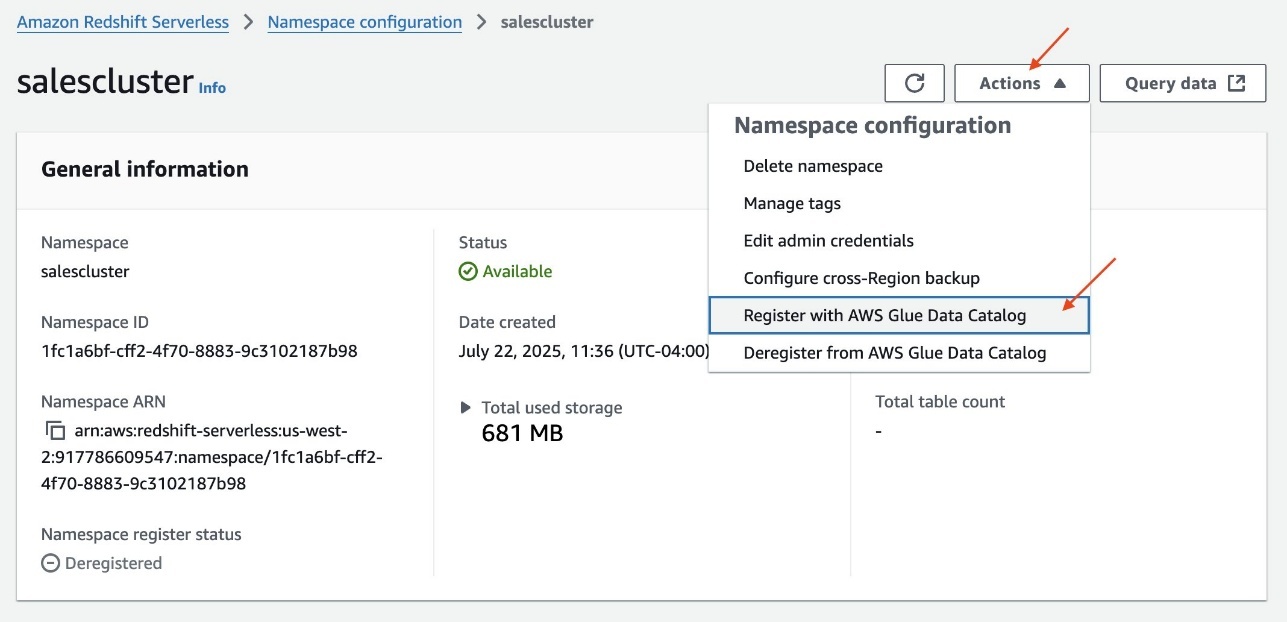
  4. On the Redshift Serverless console, open the namespace.
  5. On the Actions dropdown menu, choose Register with AWS Glue Data Catalog to integrate with the lakehouse architecture.
  6. Select the same AWS account and choose Register.

Create a catalog for Amazon Redshift

Alice completes the following steps to create a catalog for Amazon Redshift:

  1. Sign in to the Lake Formation console as the data lake administrator LHAdmin.
  2. In the navigation pane, under Data Catalog, choose Catalogs.
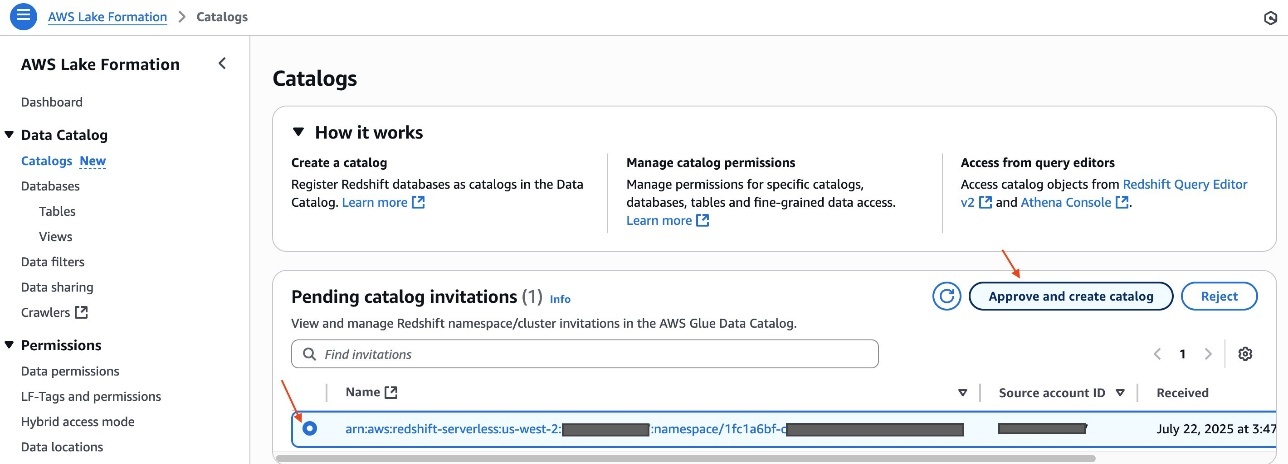
    Under Pending catalog invitations, you will see the invitation initiated from the Redshift Serverless namespace salescluster.
  3. Select the pending invitation and choose Approve and create catalog.
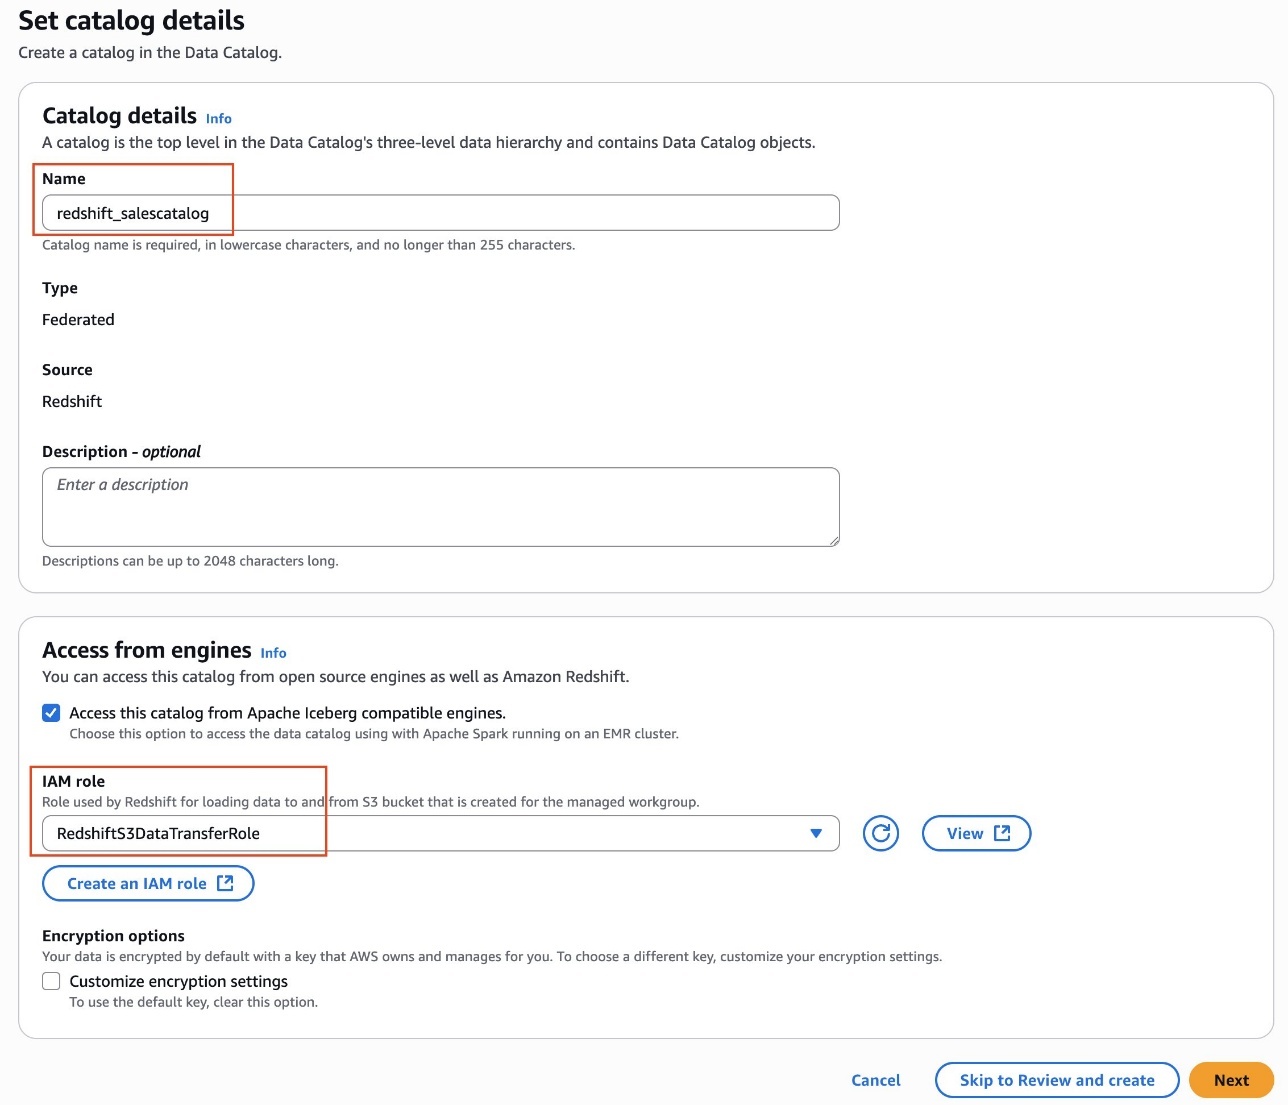
  4. Provide a name for the catalog. For example, redshift_salescatalog.
  5. Under Access from engines, select Access this catalog from Iceberg-compatible engines and choose RedshiftS3DataTransferRole for IAM role.
  6. Choose Next.
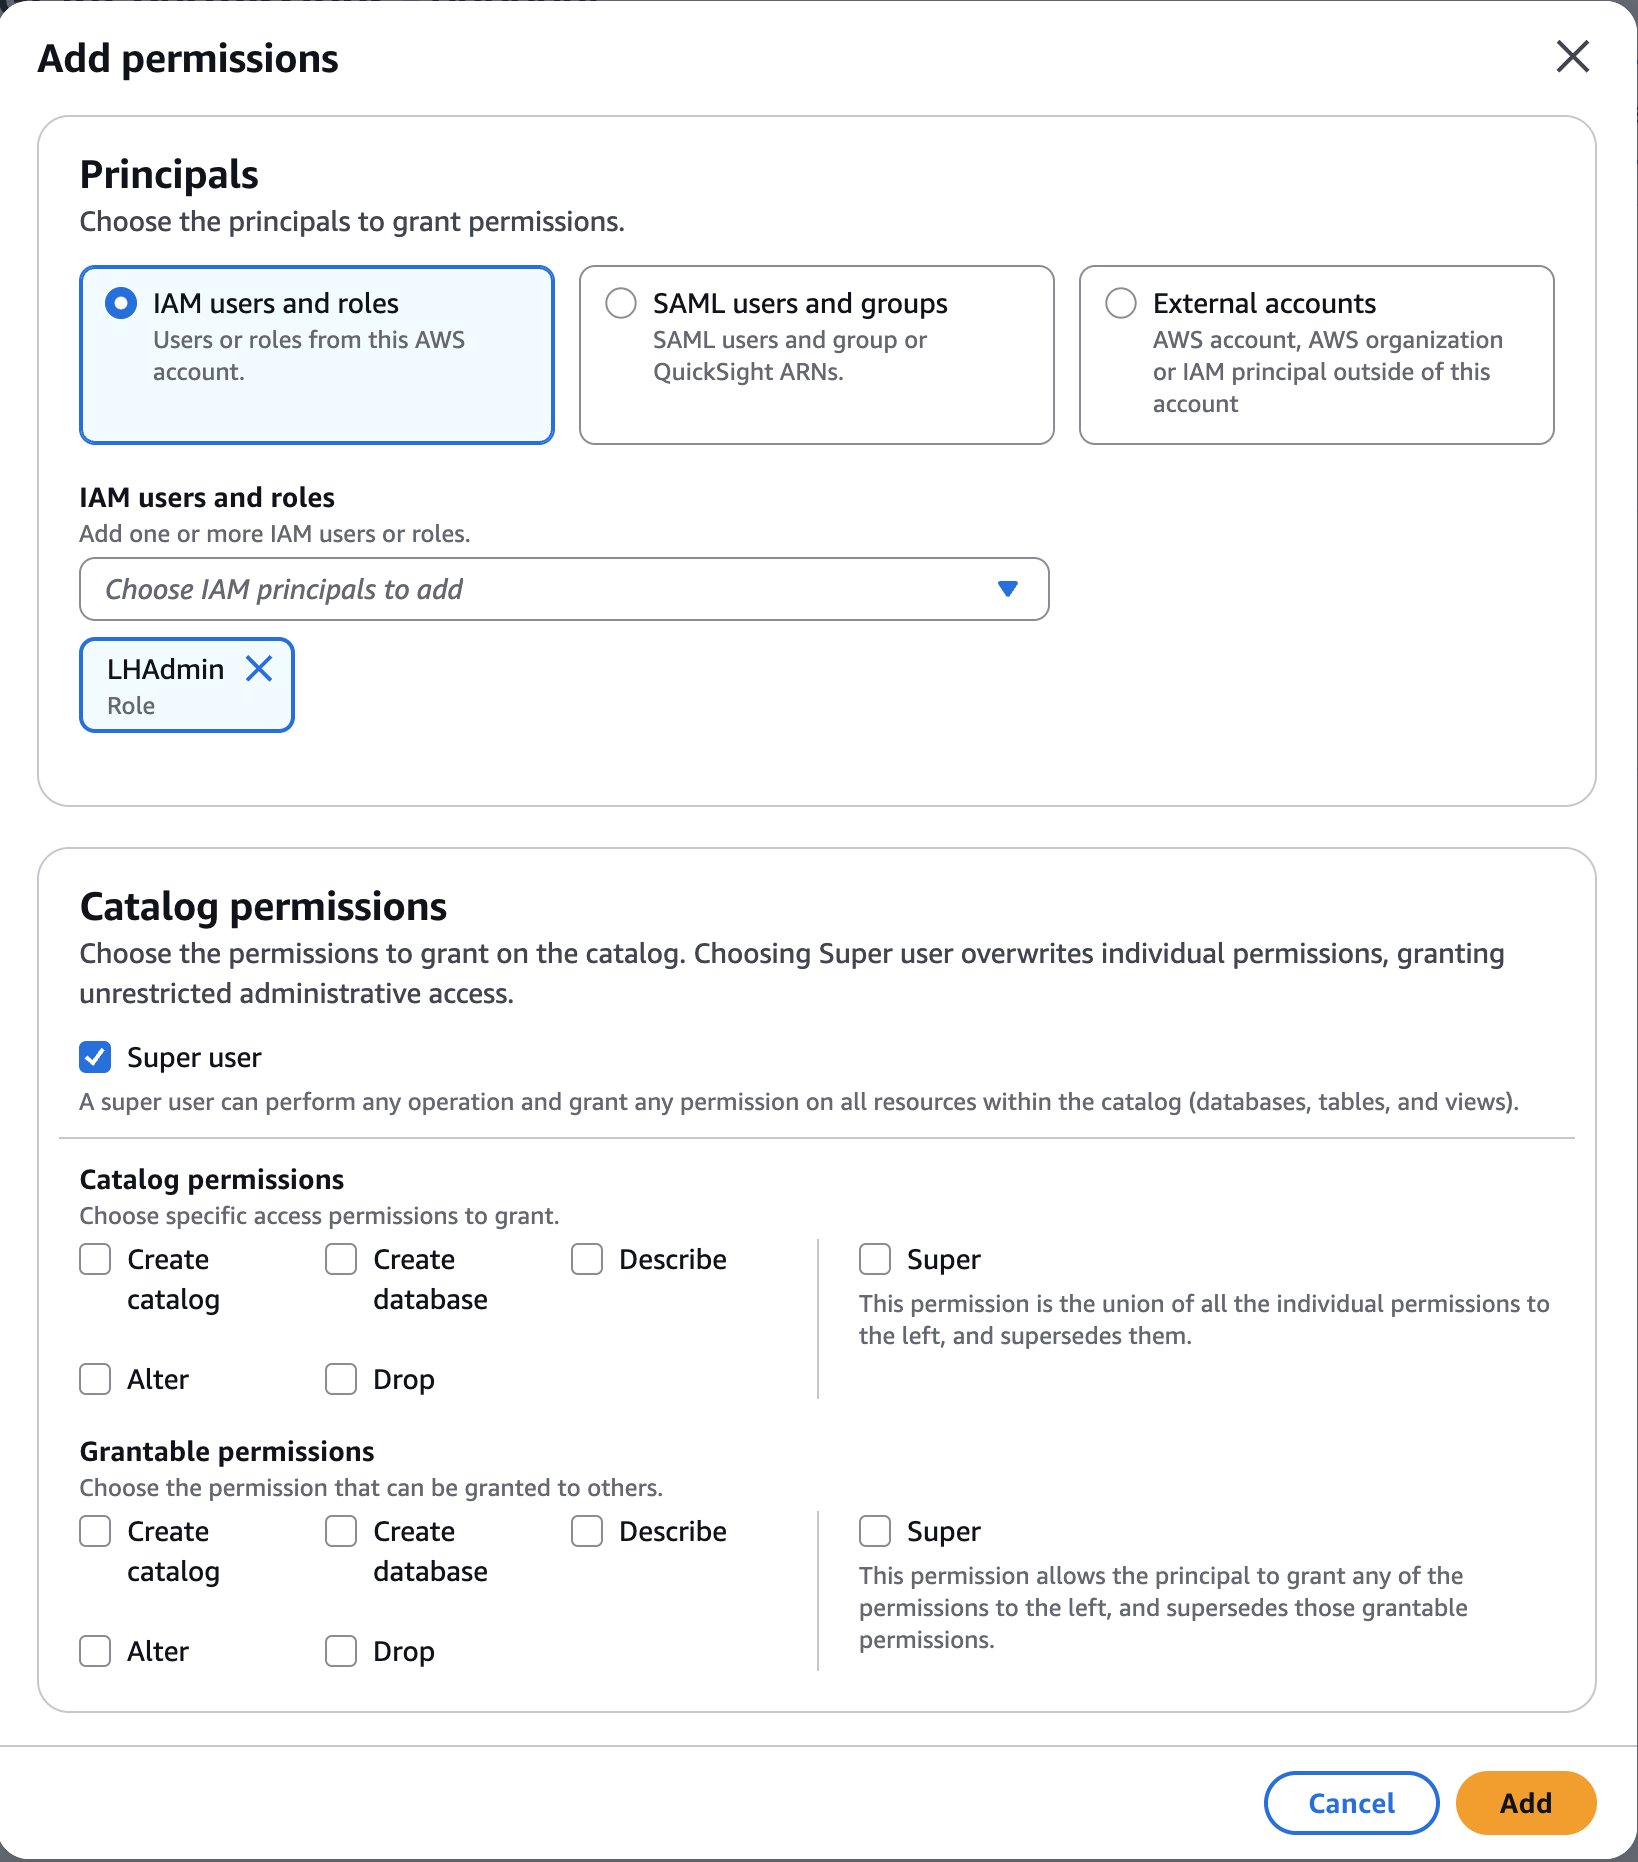
  7. Choose Add permissions.
  8. Under Principals, choose the LHAdmin role for IAM users and roles, choose Super user for Catalog permissions, and choose Add.
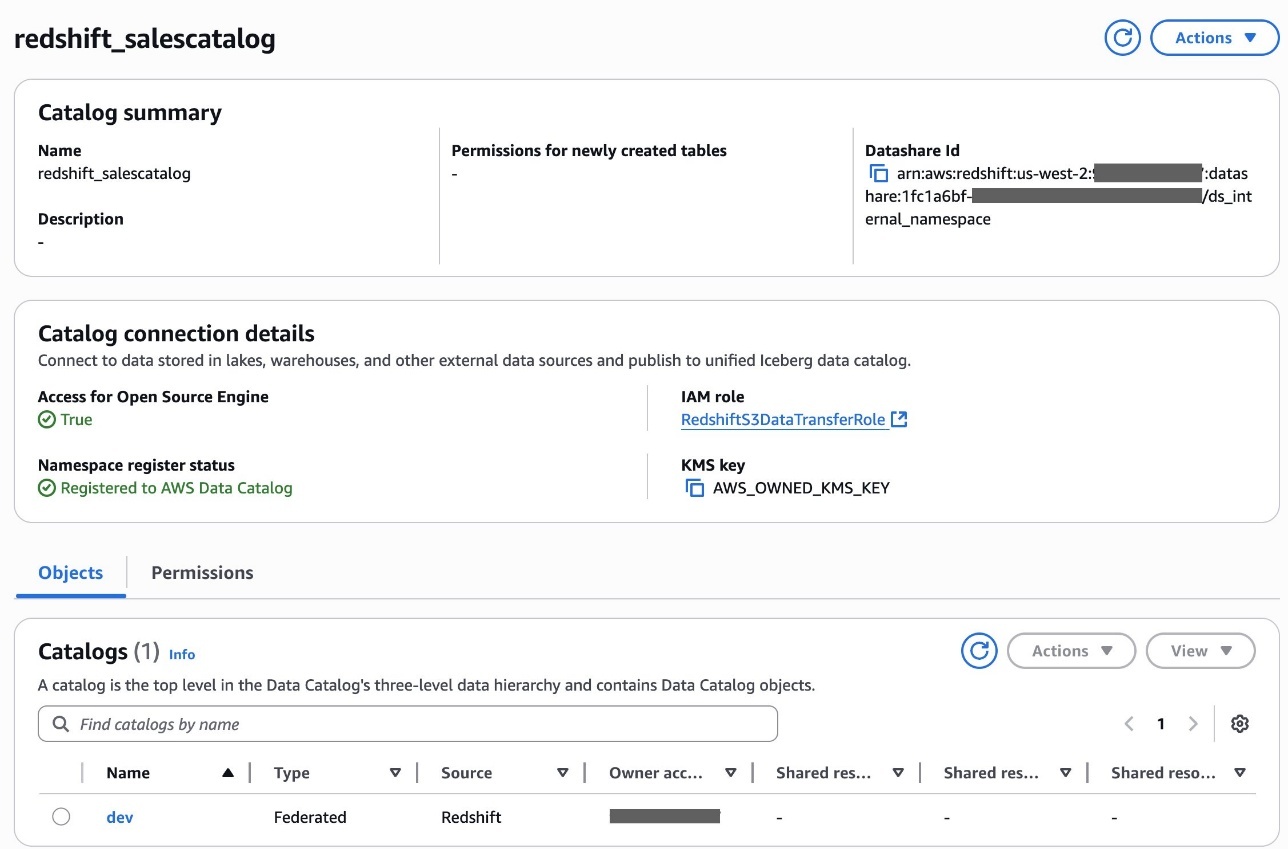
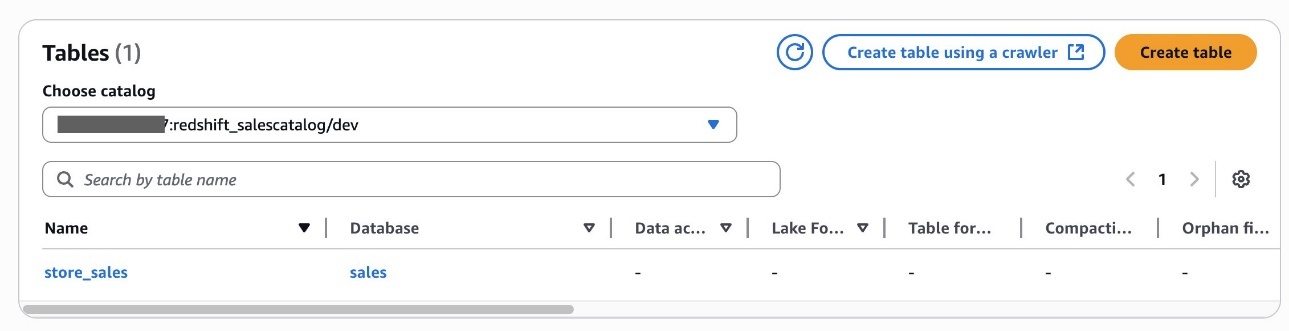
  9. Choose Create catalog.After you create the catalog redshift_salescatalog, you can inspect the sub-catalog dev, namespace and database sales, and table store_sales underneath it.

Alice has now completed creating an S3table catalog table and Redshift federated catalog table in the Data Catalog.

Delegate LF-Tags creation and resource permission to the DataSteward role

Alice completes the following steps to delegate LF-Tags creation and resource permission to Bob as DataSteward:

  1. Sign in to the Lake Formation console as the data lake administrator LHAdmin.
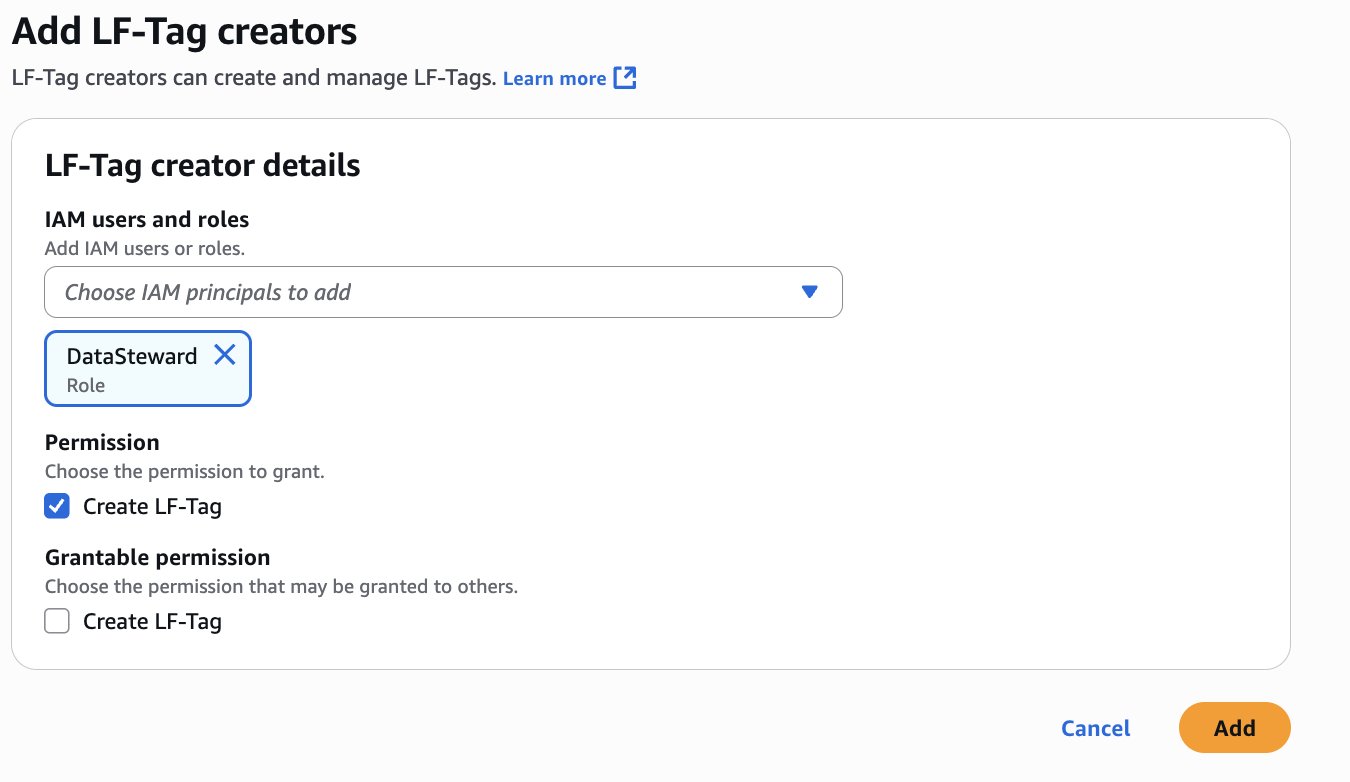
  2. In the navigation pane, choose LF Tags and permissions, then choose the LF-Tag creators tab.
  3. Choose Add LF-Tag creators.
  4. Choose DataSteward for IAM users and roles.
  5. Under Permission, select Create LF-Tag and choose Add.
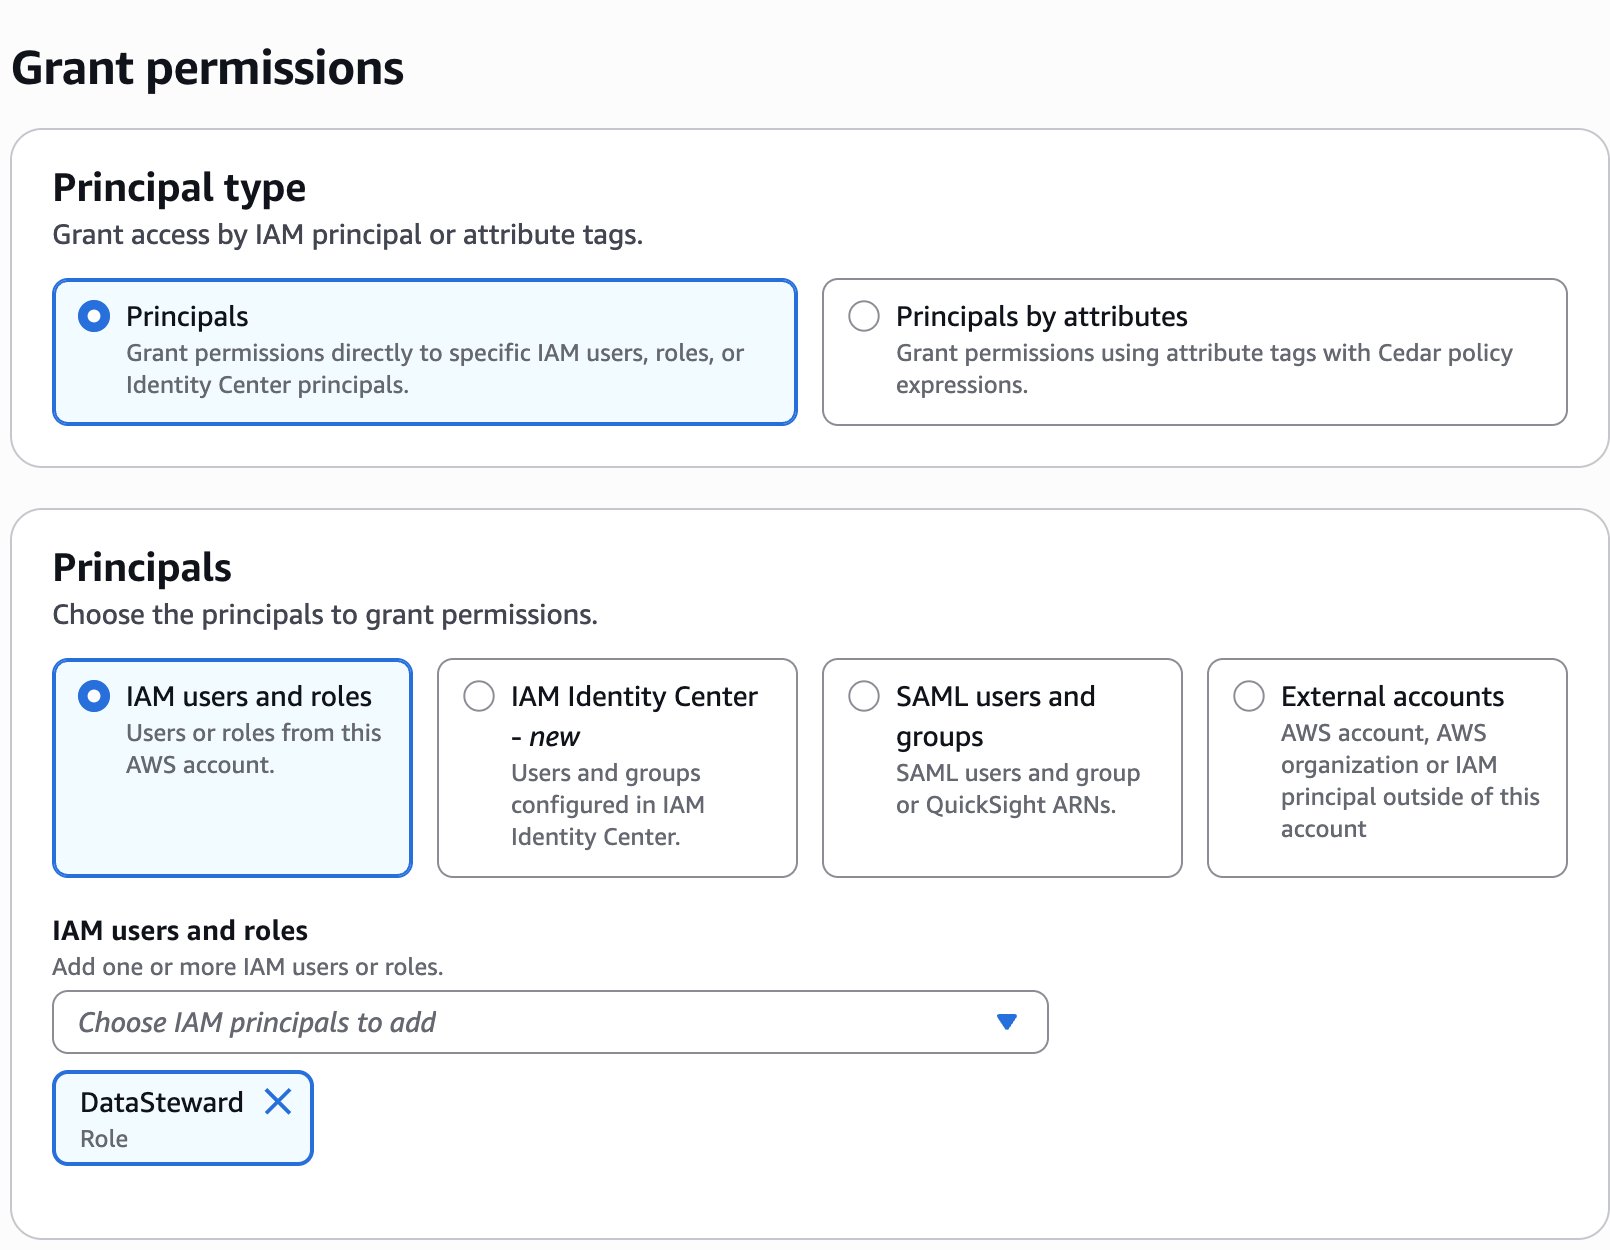
  6. In the navigation pane, choose Data permissions, then choose Grant.
  7. In the Principals section, for IAM users and roles, choose the DataSteward role.
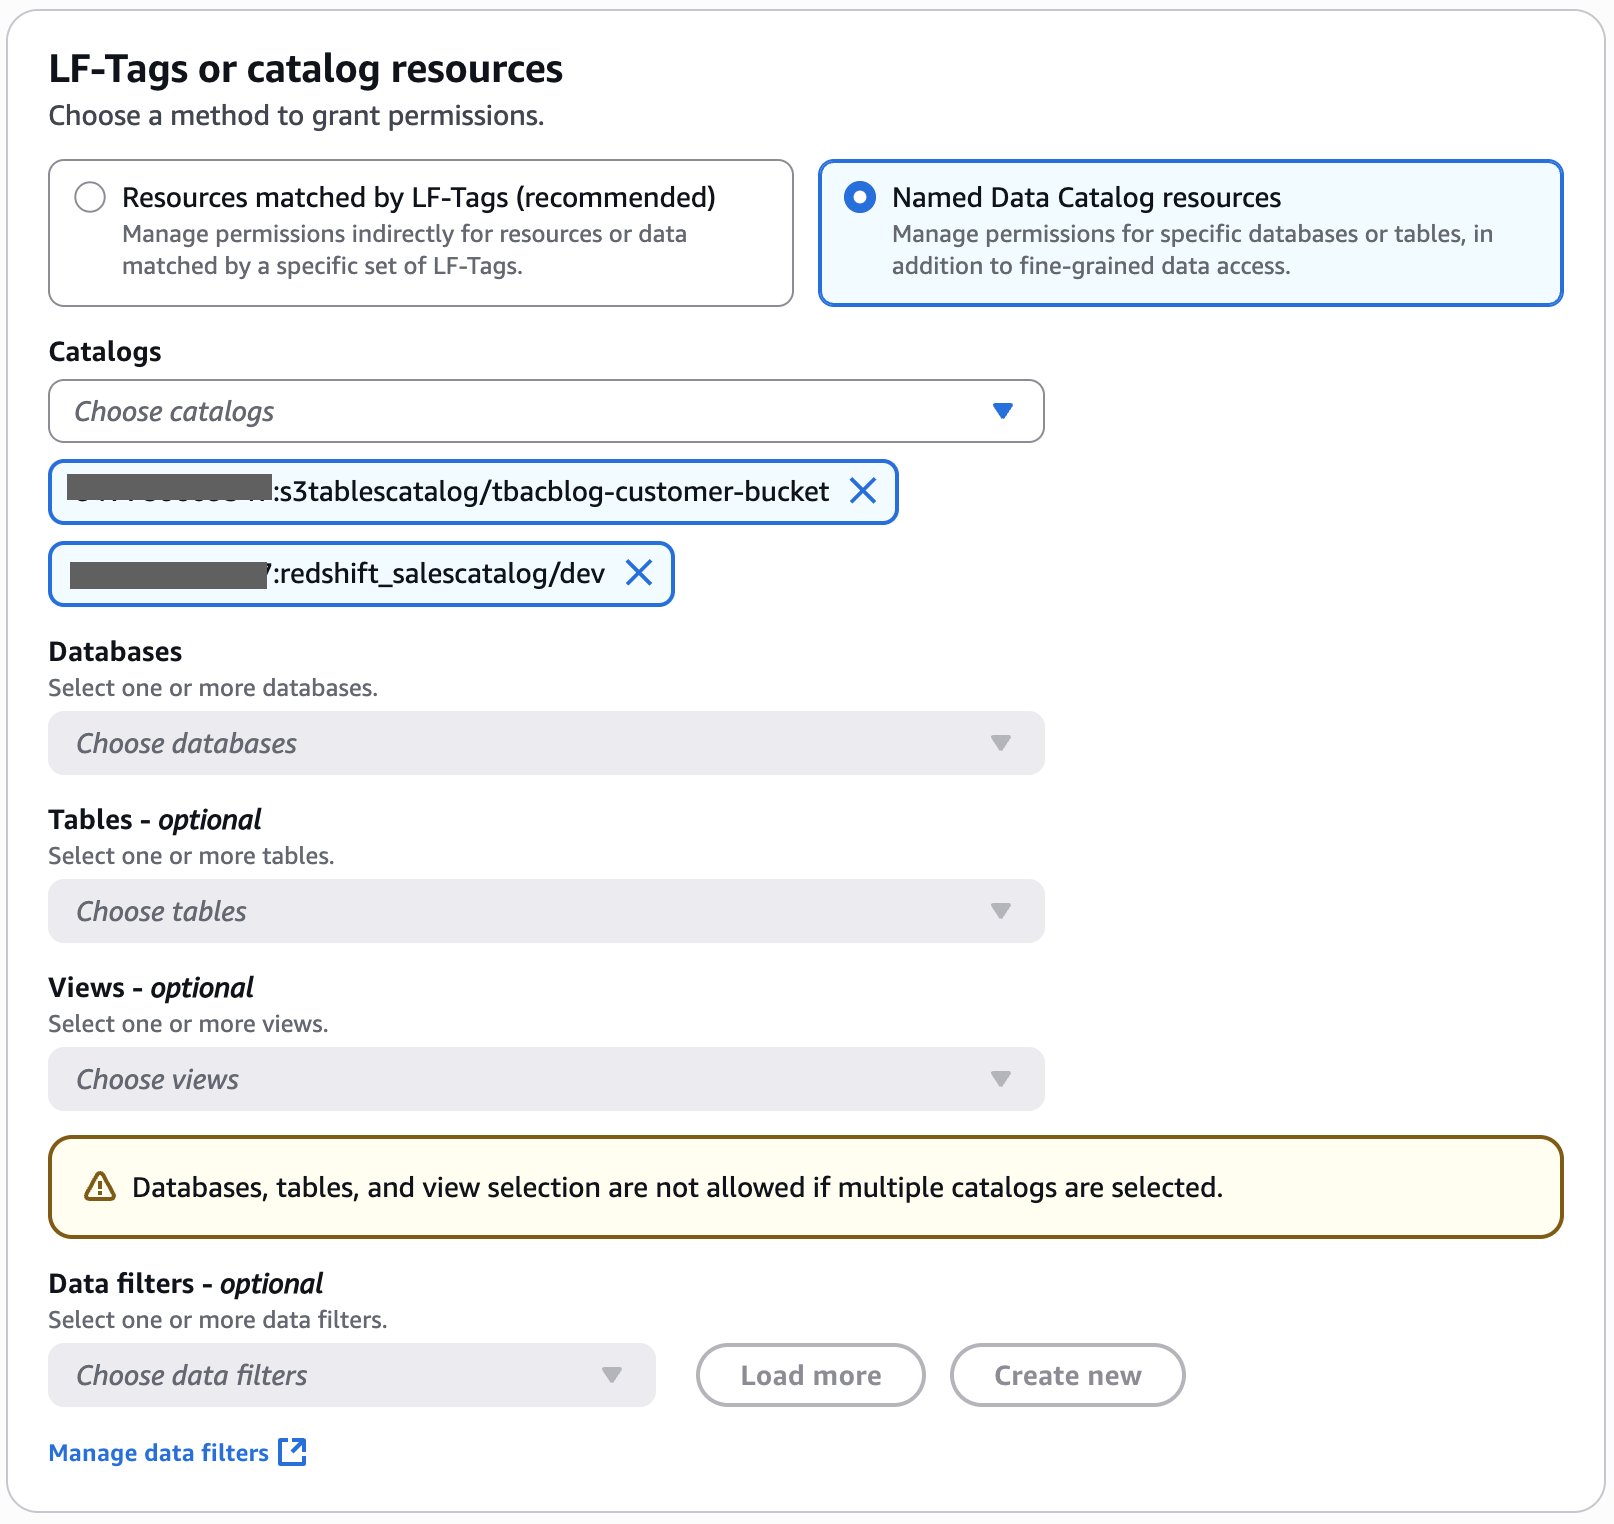
  8. In the LF-Tags or catalog resources section, select Named Data Catalog resources.
  9. Choose <account_id>:s3tablescatalog/tbacblog-customer-bucket and <account_id>:redshift_salescatalog/dev for Catalogs.
  10. In the Catalog permissions section, select Super user for permissions.
  11. Choose Grant.

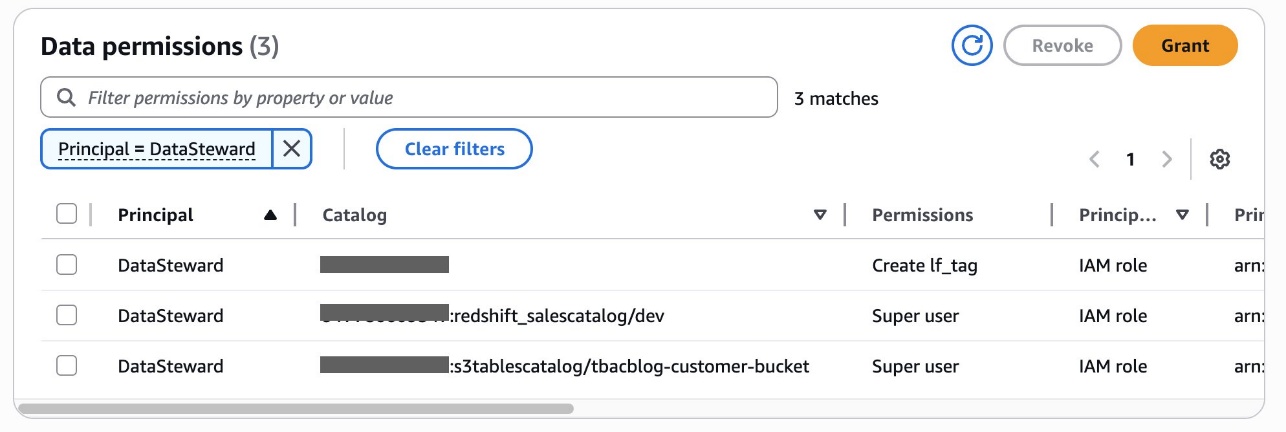
You can verify permissions for DataSteward on the Data permissions page.

Alice has now completed delegating LF-tags creation and assignment permissions to Bob, the DataSteward. She had also granted catalog level permissions to Bob.

Create LF-Tags

Bob as DataSteward completes the following steps to create LF-Tags:

  1. Sign in to the Lake Formation console as DataSteward.
  2. In the navigation pane, choose LF Tags and permissions, then choose the LF-tags tab.
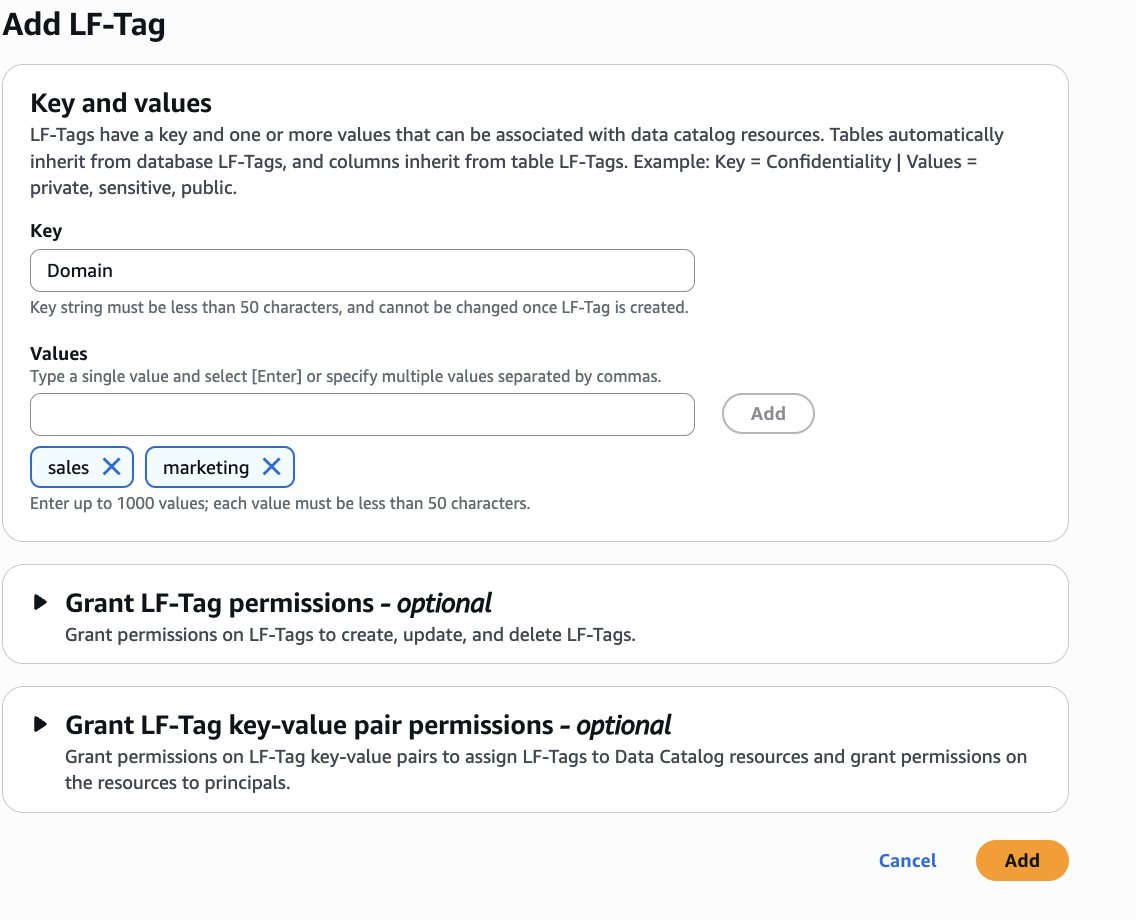
  3. Choose Add-LF-Tag.
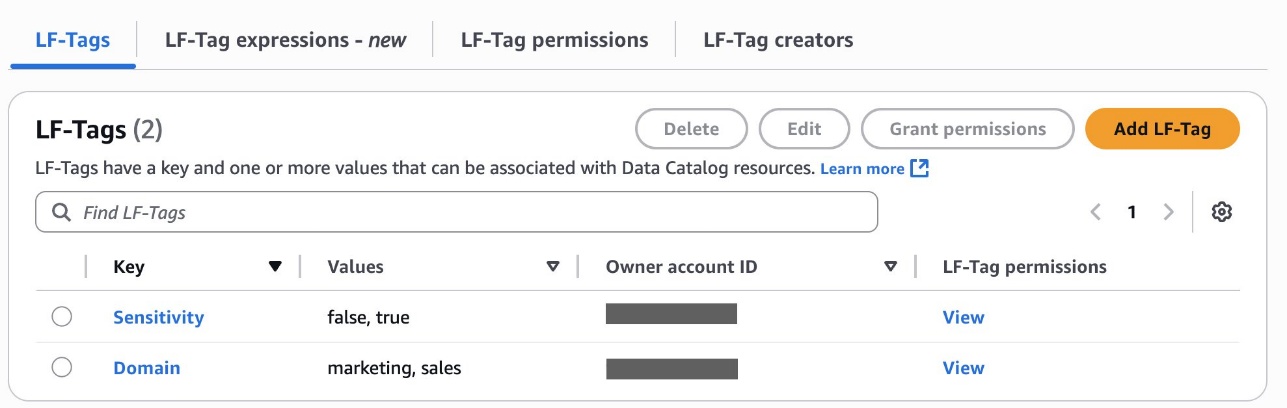
  4. Create LF tags as follows:
    1. Key: Domain and Values: sales, marketing
    2. Key: Sensitivity and Values: true, false

Assign LF-Tags to the S3 Tables database and table

Bob as DataSteward completes the following steps to assign LF-Tags to the S3 Tables database and table:

  1. In the navigation pane, choose Catalogs and choose s3tablescatalog.
  2. Choose tbacblog-customer-bucket and choose tbacblog_namespace.
  3. Choose Edit LF-Tags.
  4. Assign the following tags:
    1. Key: Domain and Value: sales
    2. Key: Sensitivity and Value: false
  5. Choose Save.
  6. On the View dropdown menu, choose Tables.
  7. Choose the customer table and choose the Schema tab.
  8. Choose Edit schema and select the columns c_first_name, c_last_name, c_email_address, and c_birth_year.
  9. Choose Edit LF-Tags and modify the tag value:
    1. Key: Sensitivity and Value: true
  10. Choose Save.

Assign LF-Tags to the Redshift database and table

Bob as DataSteward completes the following steps to assign LF-Tags to the Redshift database and table:

  1. In the navigation pane, choose Catalogs and choose salescatalog.
  2. Choose dev and select sales.
  3. Choose Edit LF-Tags and assign the following tags:
    1. Key: Domain and Value: sales
    2. Key: Sensitivity and Value: false
  4. Choose Save.

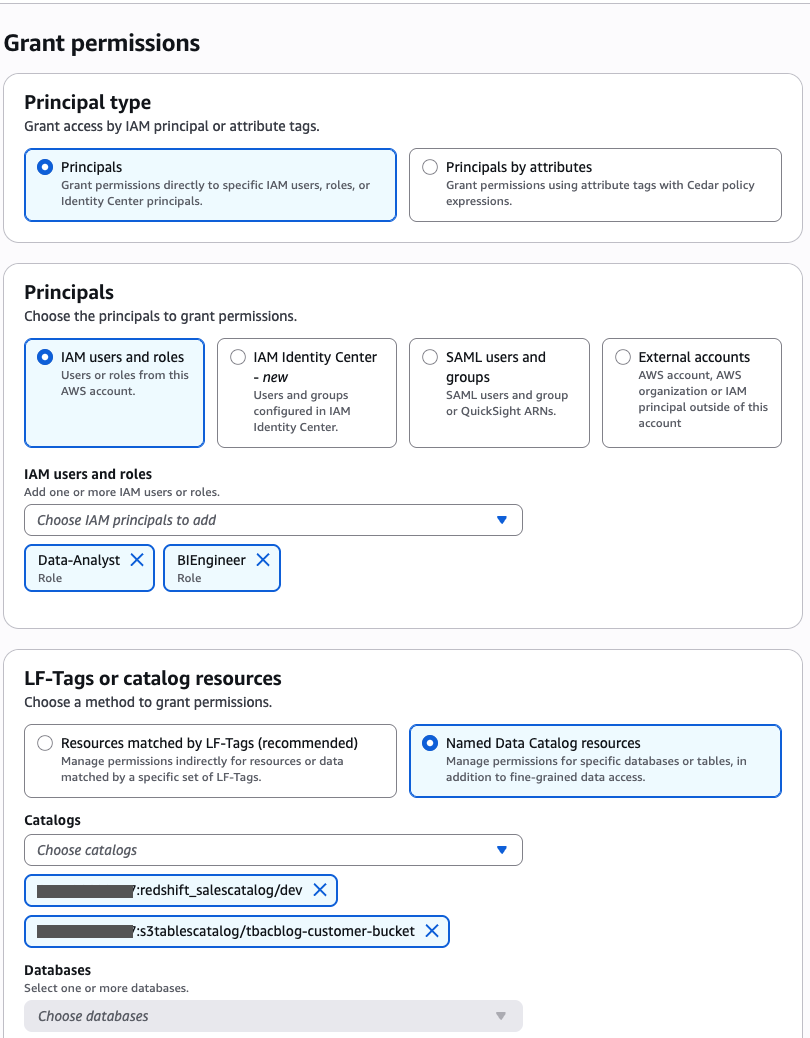
Grant catalog permission to the DataAnalyst and BIEngineer roles

Bob as DataSteward completes the following steps to grant catalog permission to the DataAnalyst and BIEngineer roles (Charlie and Doug, respectively):

  1. In the navigation pane, choose Datalake permissions, then choose Grant.
  2. In the Principals section, for IAM users and roles, choose the DataAnalyst and BIEngineer roles.
  3. In the LF-Tags or catalog resources section, select Named Data Catalog resources.
  4. For Catalogs, choose <account_id>:s3tablescatalog/tbacblog-customer-bucket and <account_id>:salescatalog/dev.
  5. In the Catalog permissions section, choose Describe for permissions.
  6. Choose Grant.

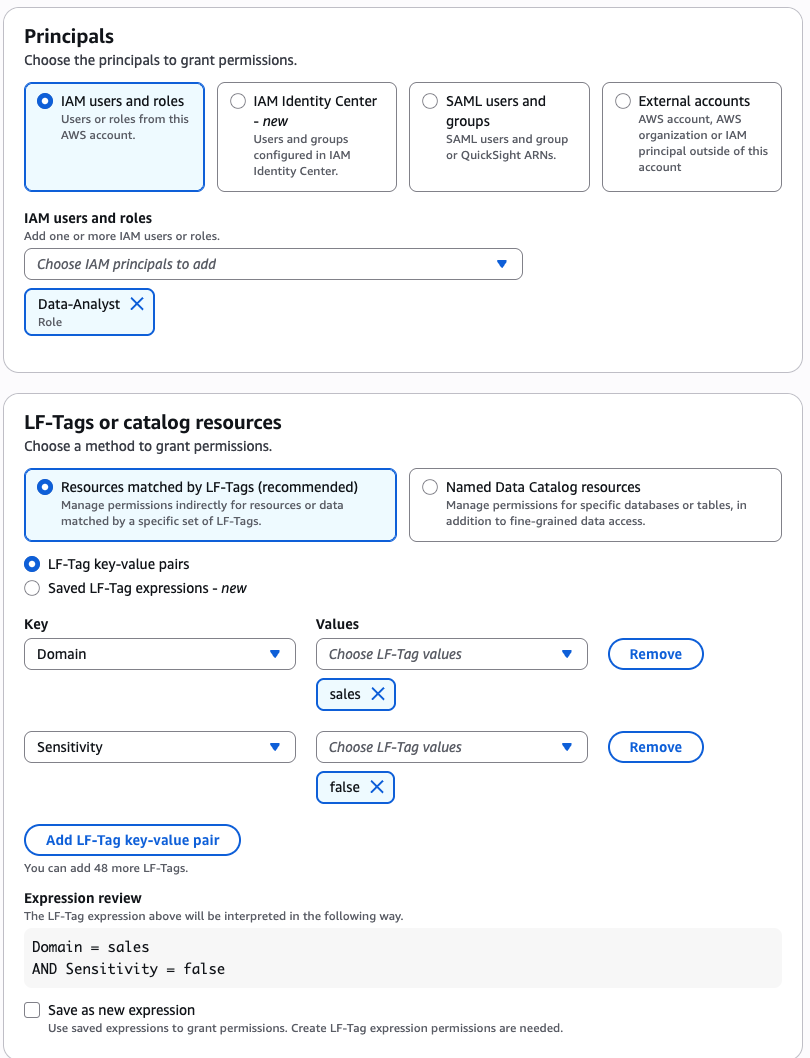
Grant permission to the DataAnalyst role for the sales domain and non-sensitive data

Bob as DataSteward completes the following steps to grant permission to the DataAnalyst role (Charlie) for the sales domain for non-sensitive data:

  1. In the navigation pane, choose Datalake permissions, then choose Grant.
  2. In the Principals section, for IAM users and roles, choose the DataAnalyst role.
  3. In the LF-Tags or catalog resources section, select Resources matched by LF-Tags and provide the following values:
    1. Key: Domain and Value: sales
    2. Key: Sensitivity and Value: false

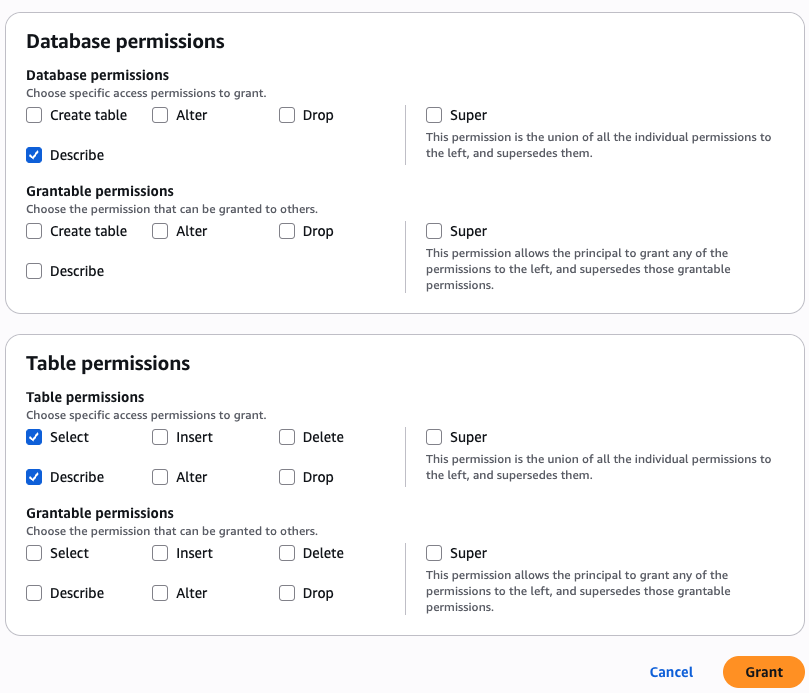
  4. In the Database permissions section, choose Describe for permissions.
  5. In the Table permissions section, select Select and Describe for permissions.
  6. Choose Grant.

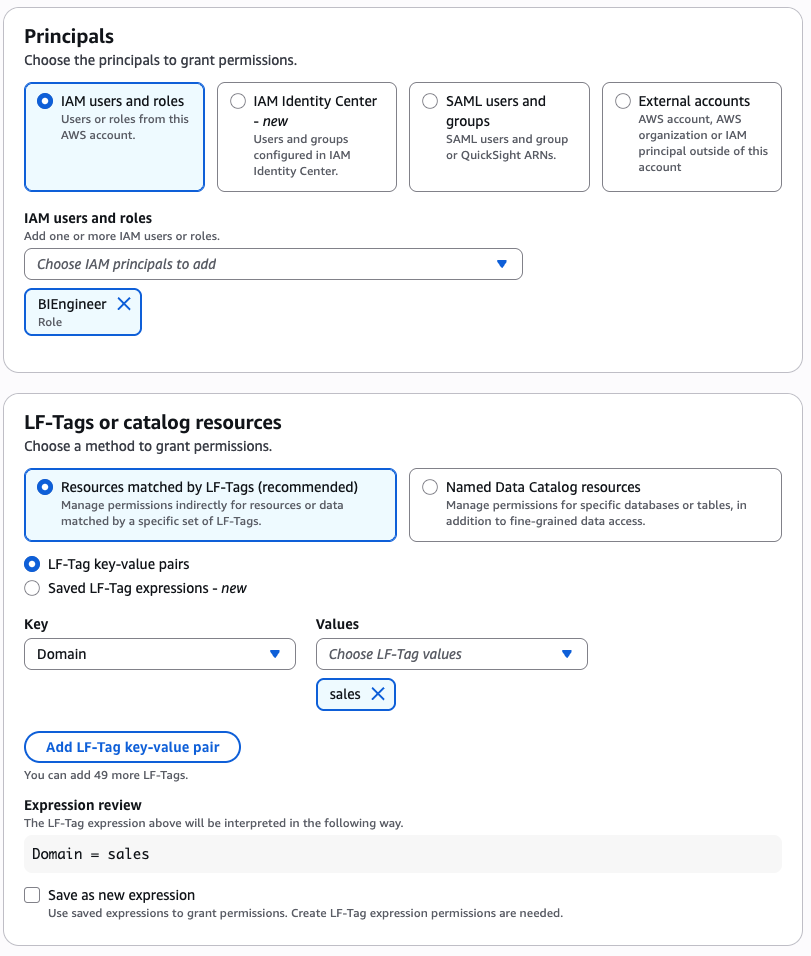
Grant permission to the BIEngineer role for sales domain data

Bob as DataSteward completes the following steps to grant permission to the BIEngineer role (Doug) for all sales domain data:

  1. In the navigation pane, choose Datalake permissions, then choose Grant.
  2. In the Principals section, for IAM users and roles, choose the BIEngineer role.
  3. In the LF-Tags or catalog resources section, select Resources matched by LF-Tags and provide the following values:
    1. Key: Domain and Value: sales
  4. In the Database permissions section, choose Describe for permissions.
  5. In the Table permissions section, select Select and Describe for permissions.
  6. Choose Grant.

This completes the steps to grant S3 Tables and Redshift federated tables permissions to various data personas using LF-TBAC.

Verify data access

In this step, we log in as individual data personas and query the lakehouse tables that are available to each persona.

Use Athena to analyze customer information as the DataAnalyst role

Charlie signs in to the Athena console as the DataAnalyst role. He runs the following sample SQL query:

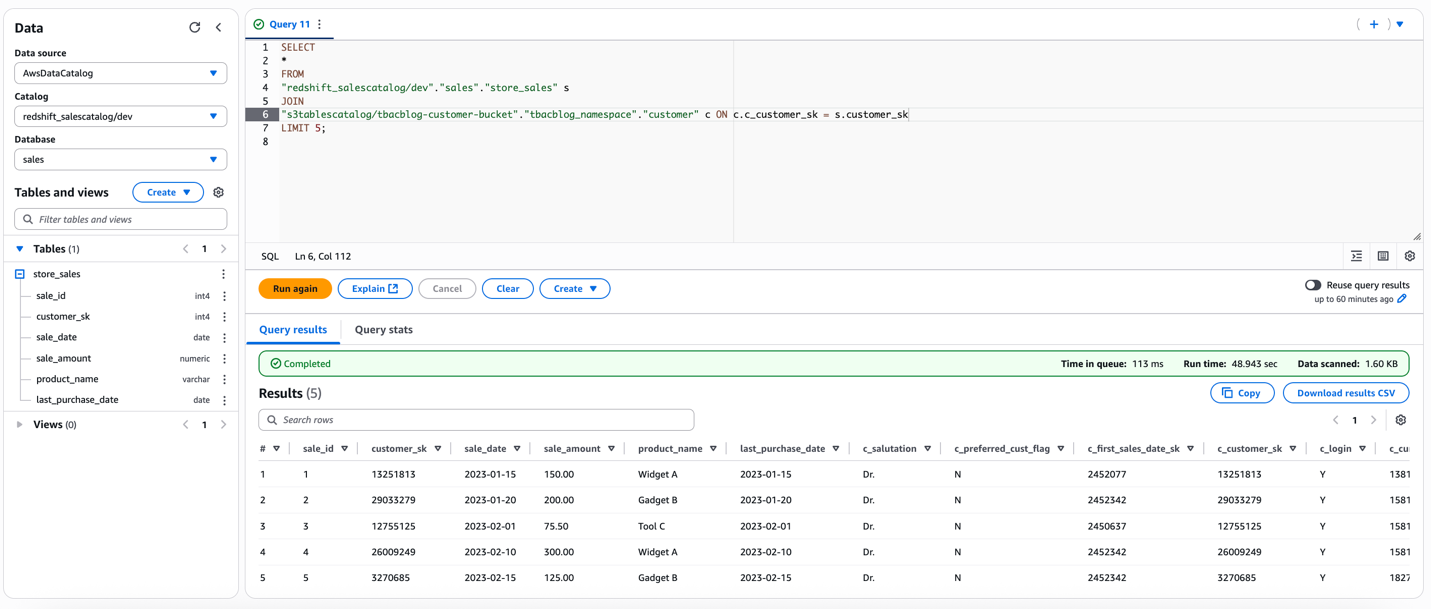
SELECT * FROM
"redshift_salescatalog/dev"."sales"."store_sales" s
JOIN
"s3tablescatalog/tbacblog-customer-bucket"."tbacblog_namespace"."customer" c 
ON c.c_customer_sk = s.customer_sk
LIMIT 5;

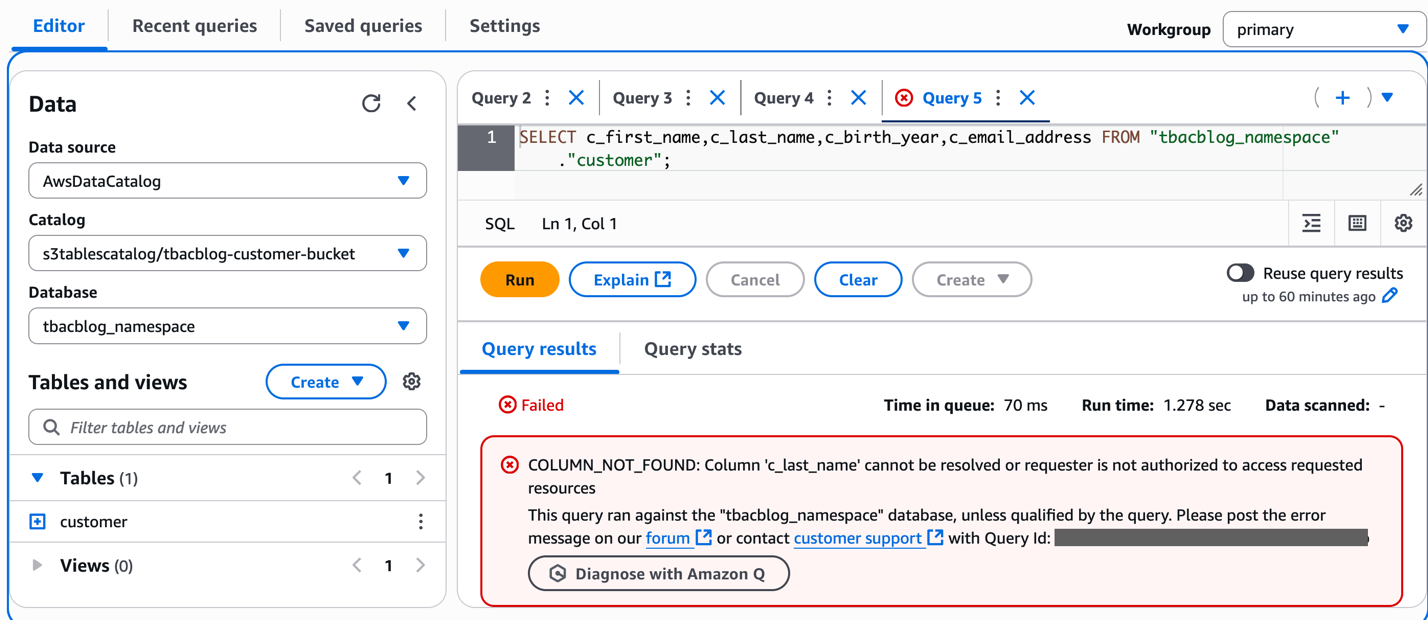
Run a sample query to access the 4 columns in the S3table customer that DataAnalyst does not have access to. You should receive an error as shown in the screenshot. This verifies column level fine grained access using LF-tags on the lakehouse tables.

Use the Redshift query editor to analyze customer data as the DataAnalyst role

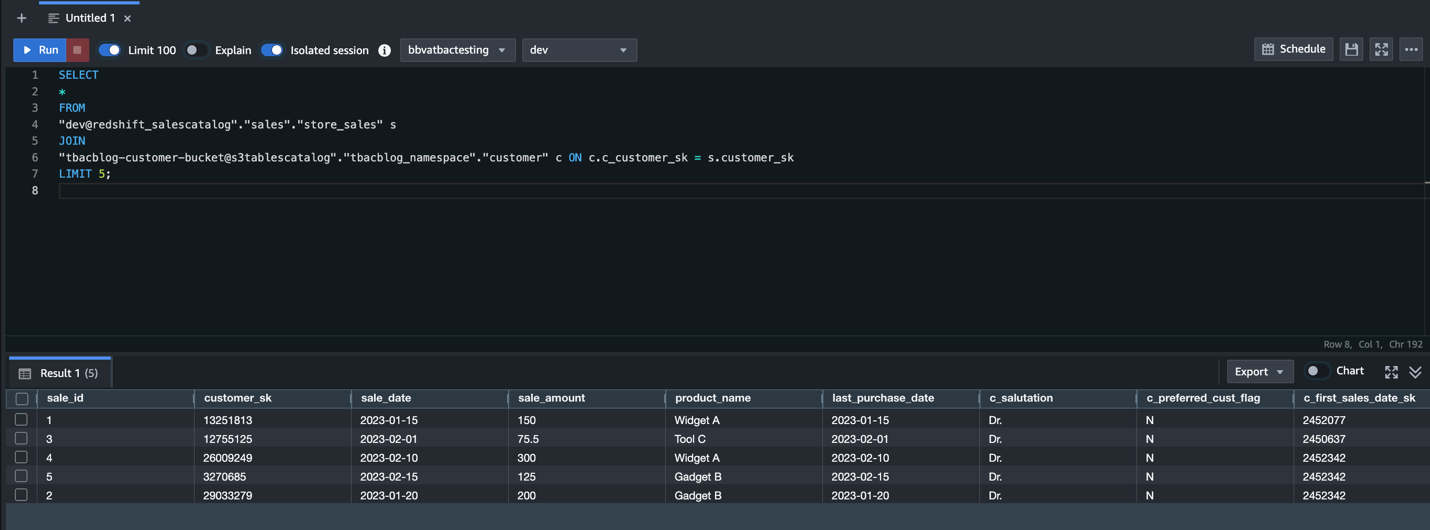
Charlie signs in to the Redshift query editor v2 as the DataAnalyst role and runs the following sample SQL query:

SELECT * FROM
"dev@redshift_salescatalog"."sales"."store_sales" s
JOIN
"tbacblog-customer-bucket@s3tablescatalog"."tbacblog_namespace"."customer" c 
ON c.c_customer_sk = s.customer_sk
LIMIT 5;

This verifies the DataAnalyst access to the lakehouse tables with LF-tags based permissions, using Redshift Spectrum

Use Amazon EMR to process customer data as the BIEngineer role

Doug uses Amazon EMR to process customer data with the BIEngineer role:

  1. Sign-in to the EMR Studio as Doug, with BIEngineer role. Ensure EMR Serverless application is attached to the workspace with BIEngineer as the EMR runtime role.
    Download the PySpark notebook tbacblog_emrs.ipynb. Upload to your studio environment.
  2. Change the account id, AWS Region and resource names as per your setup. Restart kernel and clear output.
  3. Once your pySpark kernel is ready, run the cells and verify access.This verifies access using LF-tags to the lakehouse tables as the EMR runtime role. For demonstration, we are also providing the pySpark script tbacblog_sparkscript.py that you can run as EMR batch job and Glue 5.0 ETL.

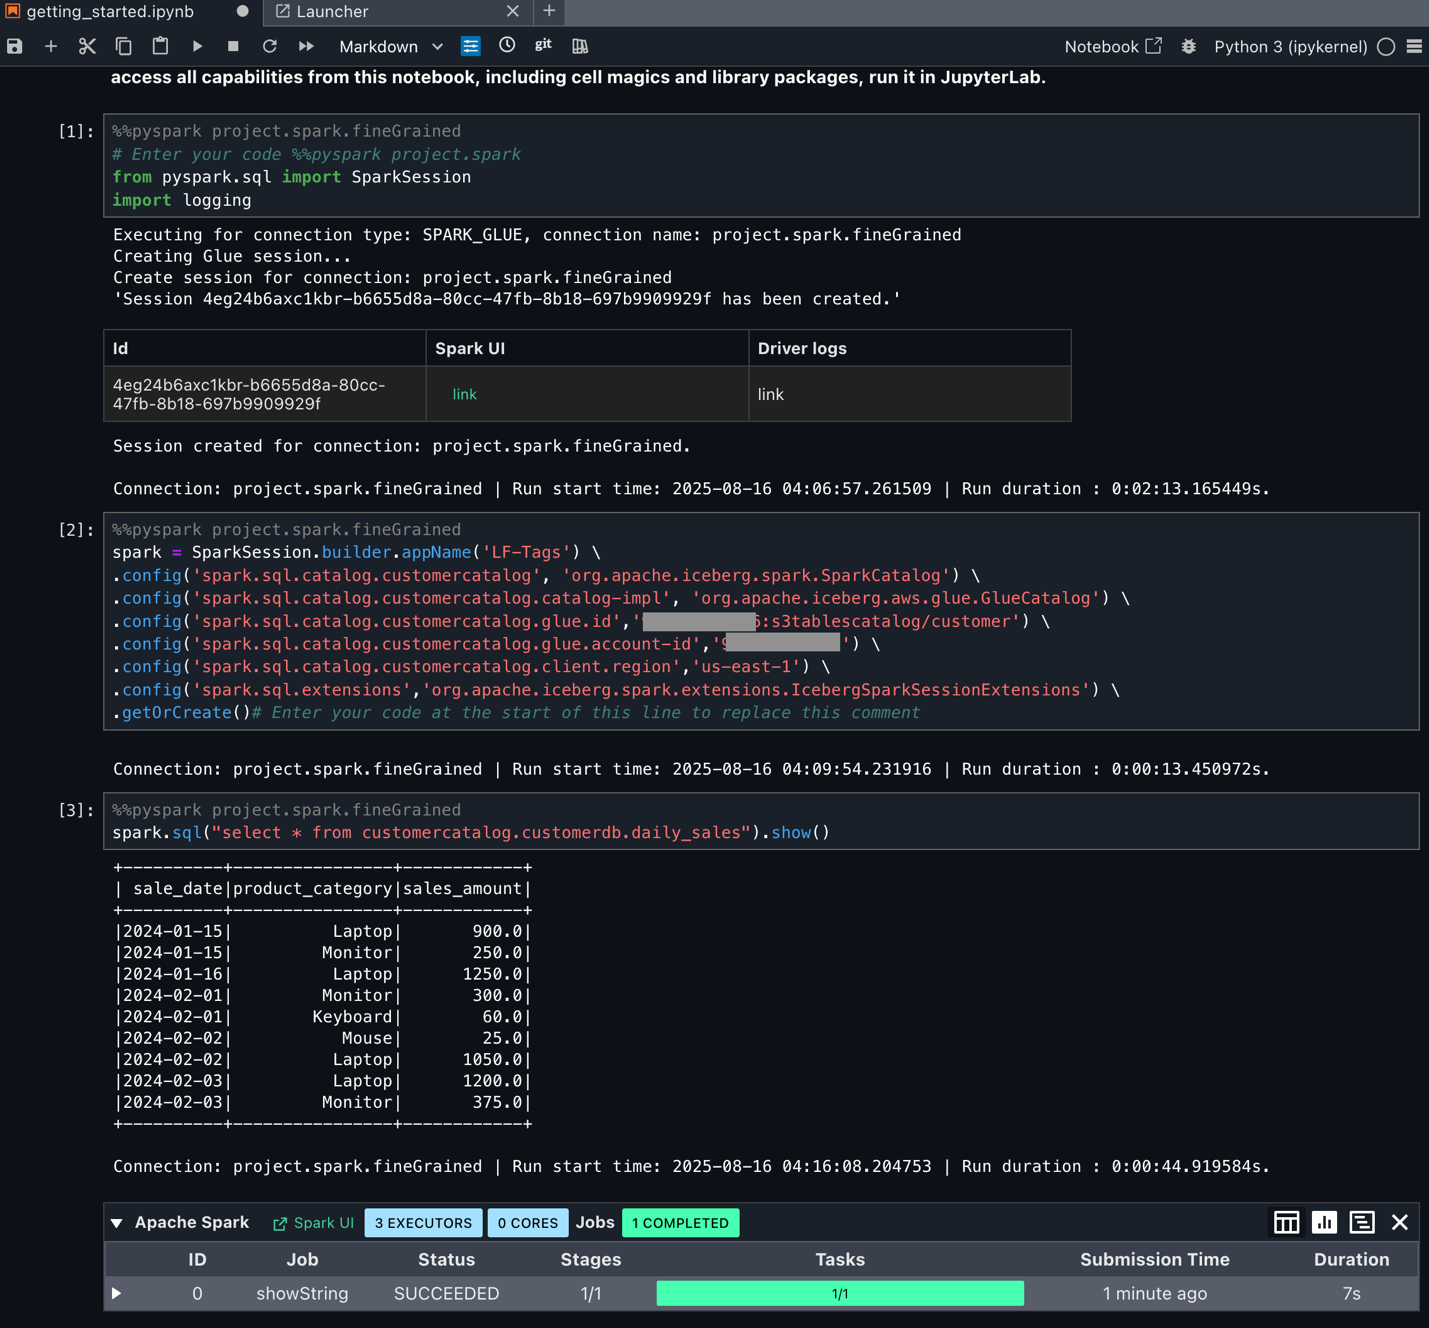
Doug has also set up Amazon SageMaker Unified Studio as covered in the blog post Accelerate your analytics with Amazon S3 Tables and Amazon SageMaker Lakehouse. Doug logs in to SageMaker Unified Studio and select previously created project to perform his analysis. He navigates to the Build options and choose JupyterLab under IDE & Applications. He uses the downloaded pyspark notebook and updates it as per his Spark query requirements. He then runs the cells by selecting compute as project.spark.fineGrained.

Doug can now start using Spark SQL and start processing data as per fine grained access controlled by the Tags.

Clean up

Complete the following steps to delete the resources you created to avoid unexpected costs:

  1. Delete the Redshift Serverless workgroups.
  2. Delete the Redshift Serverless associated namespace.
  3. Delete the EMR Studio and EMR Serverless instance.
  4. Delete the AWS Glue catalogs, databases, and tables and Lake Formation permissions.
  5. Delete the S3 Tables bucket.
  6. Empty and delete the S3 bucket.
  7. Delete the IAM roles created for this post.

Conclusion

In this post, we demonstrated how you can use Lake Formation tag-based access control with the SageMaker lakehouse architecture to achieve unified and scalable permissions to your data warehouse and data lake. Now administrators can add access permissions to federated catalogs using attributes and tags, creating automated policy enforcement that scales naturally as new assets are added to the system. This eliminates the operational overhead of manual policy updates. You can use this model for sharing resources across accounts and Regions to facilitate data sharing within and across enterprises.

We encourage AWS data lake customers to try this feature and share your feedback in the comments. To learn more about tag-based access control, visit the Lake Formation documentation.

Acknowledgment: A special thanks to everyone who contributed to the development and launch of TBAC: Joey Ghirardelli, Xinchi Li, Keshav Murthy Ramachandra, Noella Jiang, Purvaja Narayanaswamy, Sandya Krishnanand.


About the Authors

Sandeep Adwankar is a Senior Product Manager with Amazon SageMaker Lakehouse . Based in the California Bay Area, he works with customers around the globe to translate business and technical requirements into products that help customers improve how they manage, secure, and access data.

Srividya Parthasarathy is a Senior Big Data Architect with Amazon SageMaker Lakehouse. She works with the product team and customers to build robust features and solutions for their analytical data platform. She enjoys building data mesh solutions and sharing them with the community.

Aarthi Srinivasan is a Senior Big Data Architect with Amazon SageMaker Lakehouse. She works with AWS customers and partners to architect lakehouse solutions, enhance product features, and establish best practices for data governance.

Amazon SageMaker Catalog expands discoverability and governance for Amazon S3 general purpose buckets

Post Syndicated from Priya Tiruthani original https://aws.amazon.com/blogs/big-data/amazon-sagemaker-catalog-expands-discoverability-and-governance-for-amazon-s3-general-purpose-buckets/

In July 2025, Amazon SageMaker announced support for Amazon Simple Storage Service (Amazon S3) general purpose buckets and prefixes in Amazon SageMaker Catalog that delivers fine-grained access control and permissions through S3 Access Grants. This integration addresses the challenge data teams face when manually managing data discovery and Amazon S3 permissions as separate workflows. Data consumers, such as data scientists, engineers, and business analysts, can now discover and access S3 buckets or prefixes data assets through SageMaker Catalog, while administrators can maintain granular access controls using S3 Access Grants permissions.

Building upon existing SageMaker support for structured data in Amazon S3 Tables buckets, the added support for S3 general purpose buckets makes it straightforward for teams to find, access, and collaborate on different types of data, including unstructured data such as documents, images, audio, and video, while providing access management. Data administrators and data stewards can now implement fine-grained access permissions for a bucket or a prefix using S3 Access Grants, supporting secure and appropriate data usage across their organization.

In this post, we explore how this integration addresses key challenges our customers have shared with us, and how data producers, such as administrators and data engineers, can seamlessly share and govern S3 buckets and prefixes using S3 Access Grants, while making it readily discoverable for data consumers. We walk you through a practical example of bringing Amazon S3 data into your projects and implementing effective governance for both analytics and generative AI workflows.

Challenges in working with unstructured data

Organizations face challenges in maximizing the value of their unstructured data assets. Although customers want to incorporate insights derived from unstructured data for comprehensive analysis, they often resort to building bespoke integrations to extract structured information from unstructured sources, leading to inefficient and fragmented solutions. Three critical roadblocks have historically hindered enterprises:

  • Organizations struggle to maintain a catalog that offers equal discoverability for both structured and unstructured data, often resulting in separate systems for different data types.
  • Data consumers throughout organizations want to analyze unstructured data using familiar tools like notebooks, just as they do with structured data, but are forced to use separate interfaces and workflows instead.
  • Working with unstructured data lacks streamlined access management—users who discover relevant data can’t readily request access from owners, load information into analytics tools, or collaborate with colleagues directly from the workspaces or projects.

Amazon S3 unstructured data as a managed asset in Amazon SageMaker

SageMaker Catalog now supports S3 general purpose buckets. Data producers can publish S3 buckets and prefixes as S3 Object Collection assets, making those assets searchable and discoverable. As managed S3 Object Collection assets in SageMaker Catalog, access permissions are automatically handled using S3 Access Grants when data consumer teams subscribe to cataloged datasets, replacing bespoke data discovery and permission management workflows. Data producers can add business context to technical metadata, including glossary terms and descriptions. Data consumers can search, review, and request access to data assets through a unified workflow. Teams can then collaborate in SageMaker projects, incorporating datasets and conducting analysis while maintaining security and governance standards.The key benefits in the simplified discoverability and access to S3 data in SageMaker Catalog include:

  • Seamless S3 data integration – You can use existing Amazon S3 data in SageMaker without migration or restructuring
  • Enhanced cataloging and governance – SageMaker Catalog facilitates data publishing, discovery, and subscription with business metadata and security controls
  • Improved data sharing – Cataloged Amazon S3 data becomes discoverable organization-wide, accelerating insights and collaboration
  • Self-service data access – SageMaker provides tools for data preparation, ETL (extract, transform, and load), and connectivity from various sources, supporting faster analytics and AI solution development

With these benefits, you can accelerate time-to-insight and unlock the full potential of organizational data assets across teams.

Customer spotlight

Across industries, the true power of data emerges when organizations can seamlessly connect and analyze different types of information across their operations. Bayer, a leading pharmaceutical and biotechnology company, has vast sets of unstructured data organized across multiple S3 buckets and prefixes.

“Bringing a new drug to market is widely known across the industry to be a lengthy and expensive process, often taking 10–15 years and costing $1–2 billion on average, with a low overall success rate ranging from around 8% to 12%. SageMaker now allows us to easily discover and securely access data, structured and unstructured, while maintaining governance controls using S3 Access Grants. With SageMaker Catalog, we now have a streamlined approach to data management that enables us to combine datasets, both structured and unstructured, reducing research time and increasing productivity throughout the drug development lifecycle,” said Avinash Erupaka, Principal Engineer Lead, Bayer Pharma Drug Innovation Platform.

Solution overview

In life sciences organizations, unstructured and semi-structured data files are prevalent in research, development, bio-manufacturing, and diagnostics divisions. These might include digital pathology images, genetic sequence data, microwell plate readouts, analytical spectra, and chromatograms. Along with unstructured and semi-structured data, data engineers collect various business metadata, including study, project, laboratory protocol, and assay information, and operational metadata, including algorithmic steps, compute tasks, and process outputs.Scientists and business users can use SageMaker Catalog search for data assets using keywords that are found in the associated business metadata and operational metadata that are captured as metadata forms. For example, there might be searches for sample ID, experiment ID, group, platform, file names, dates, or keywords within the experimental description. These searches return a list of data assets that have association with those keywords, which are collections of S3 objects. Scientists and business users are given access to those collections of S3 objects.In the following sections, we walk through the setup step-by-step. We use the example of digital pathology images use case from the life sciences industry to demonstrate how researchers discover and get access to S3 objects using SageMaker.

Prerequisites

If you’re new to SageMaker, refer to the Amazon SageMaker User Guide to get started.

To follow along with this post, refer to Setting up Amazon SageMaker to set up a domain and create projects. This domain setup and project creation is a prerequisite for the other tasks in SageMaker.

Get data ready in Amazon S3

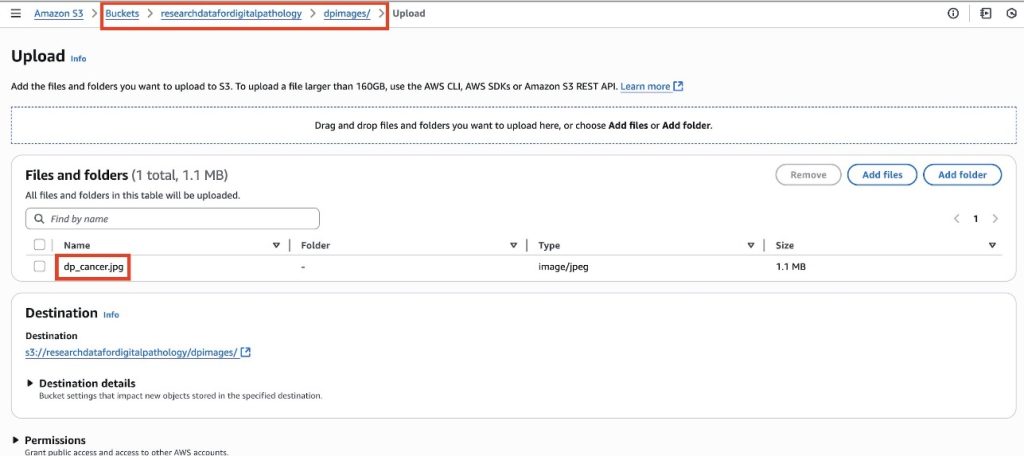
To store digital pathology images, create an S3 bucket (for example, researchdatafordigitalpathology), create a folder (for example, dpimages) under it, and upload digital pathology images. Ideally, you will have a collection of images under a given prefix, but for this example, we have chosen just one image file (dp_cancer.jpg). For instructions to create a bucket, refer to Creating a general purpose bucket.

Set up a data producer project

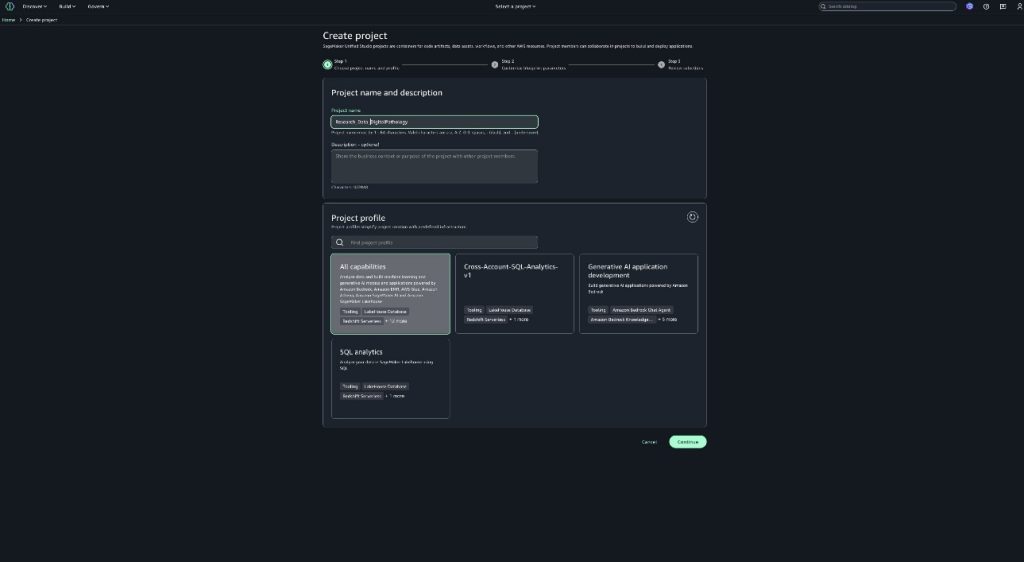
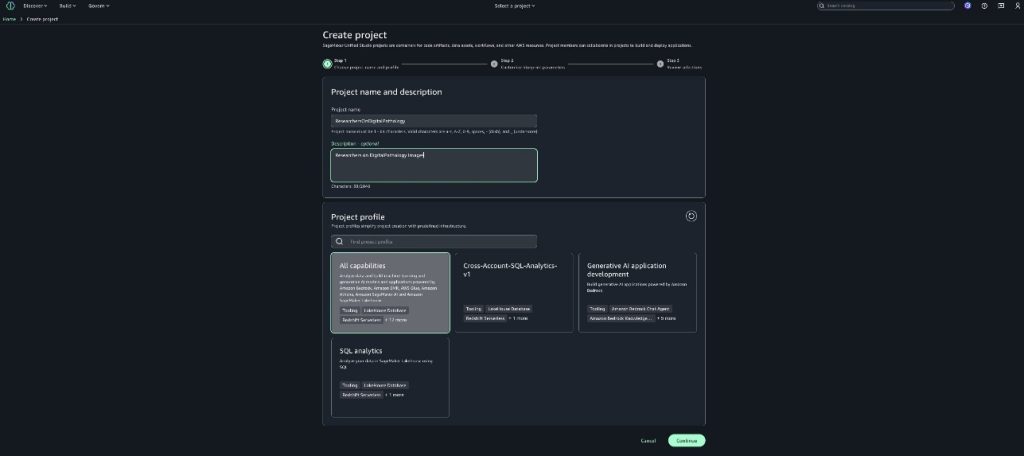
For data engineers, create a producer project in Amazon SageMaker Unified Studio to create digital pathology images as data assets. For more details on how to create projects, refer to Create a project. Add data engineers as members of the projects. For instructions to add members, refer to Add project members.

Add an Amazon S3 location

To add the collection of digital pathology images (to bring your own S3 buckets), complete the following steps:

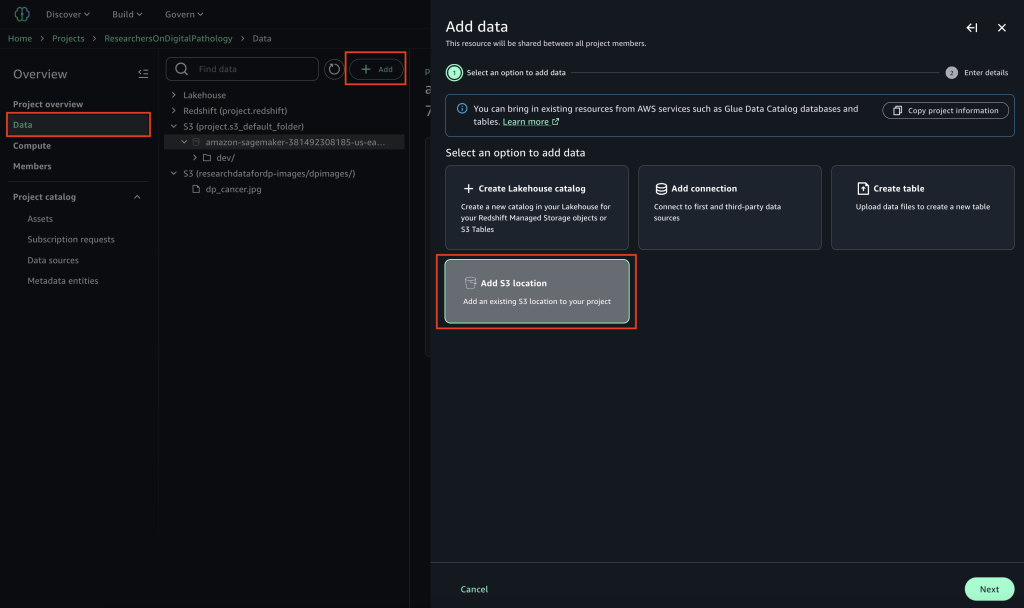
  1. In SageMaker Unified Studio, go to the project where you want to add Amazon S3.
  2. Choose Data in the navigation pane, then choose the plus sign.
  3. On the Add data page, choose Add S3 location, then choose Next.

To obtain the details to create a connection, you can choose from two options:

  • Using the project role:
    • You, the project user, retrieves the project role and shares it with the AWS Management Console admin.
    • The admin opens the AWS Identity and Access Management (IAM) console to update the project role with permissions.
    • The admin opens the Amazon S3 console and adds a CORS policy to each bucket.
  • Using an access role Amazon Resource Name (ARN), which is required for cross-account:
    • You, the project user, shares the project ID and project role with the admin and requests access to the S3 bucket.
    • The admin creates an access role (or uses an existing role) with permissions, adds a trust policy to the project, and tags it with the project ID.
    • The admin opens the Amazon S3 console and adds a CORS policy to the bucket.
    • The admin sends the Amazon S3 URI and access role details back to you.

After you have necessary permissions configured for the Amazon S3 location and project role, continue with the remaining steps.

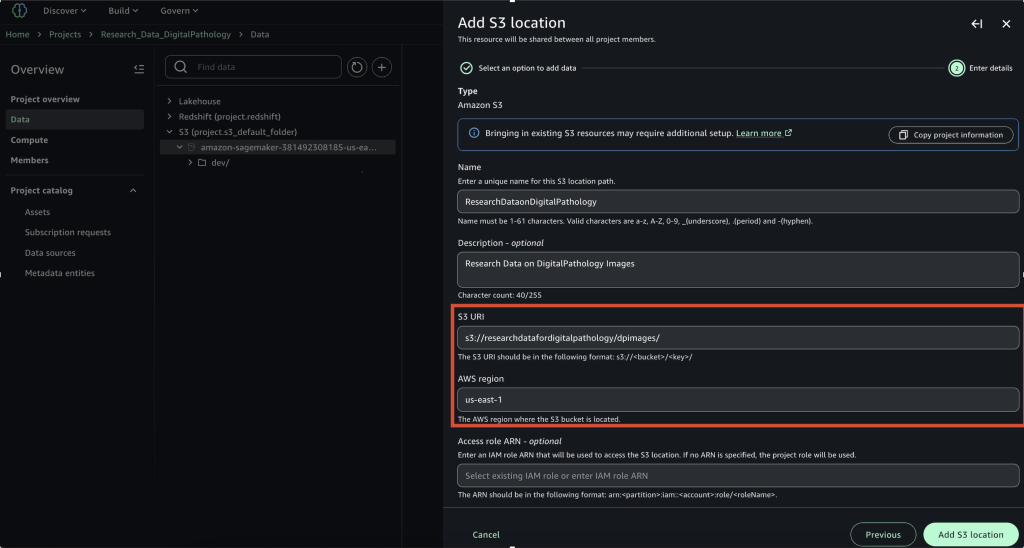
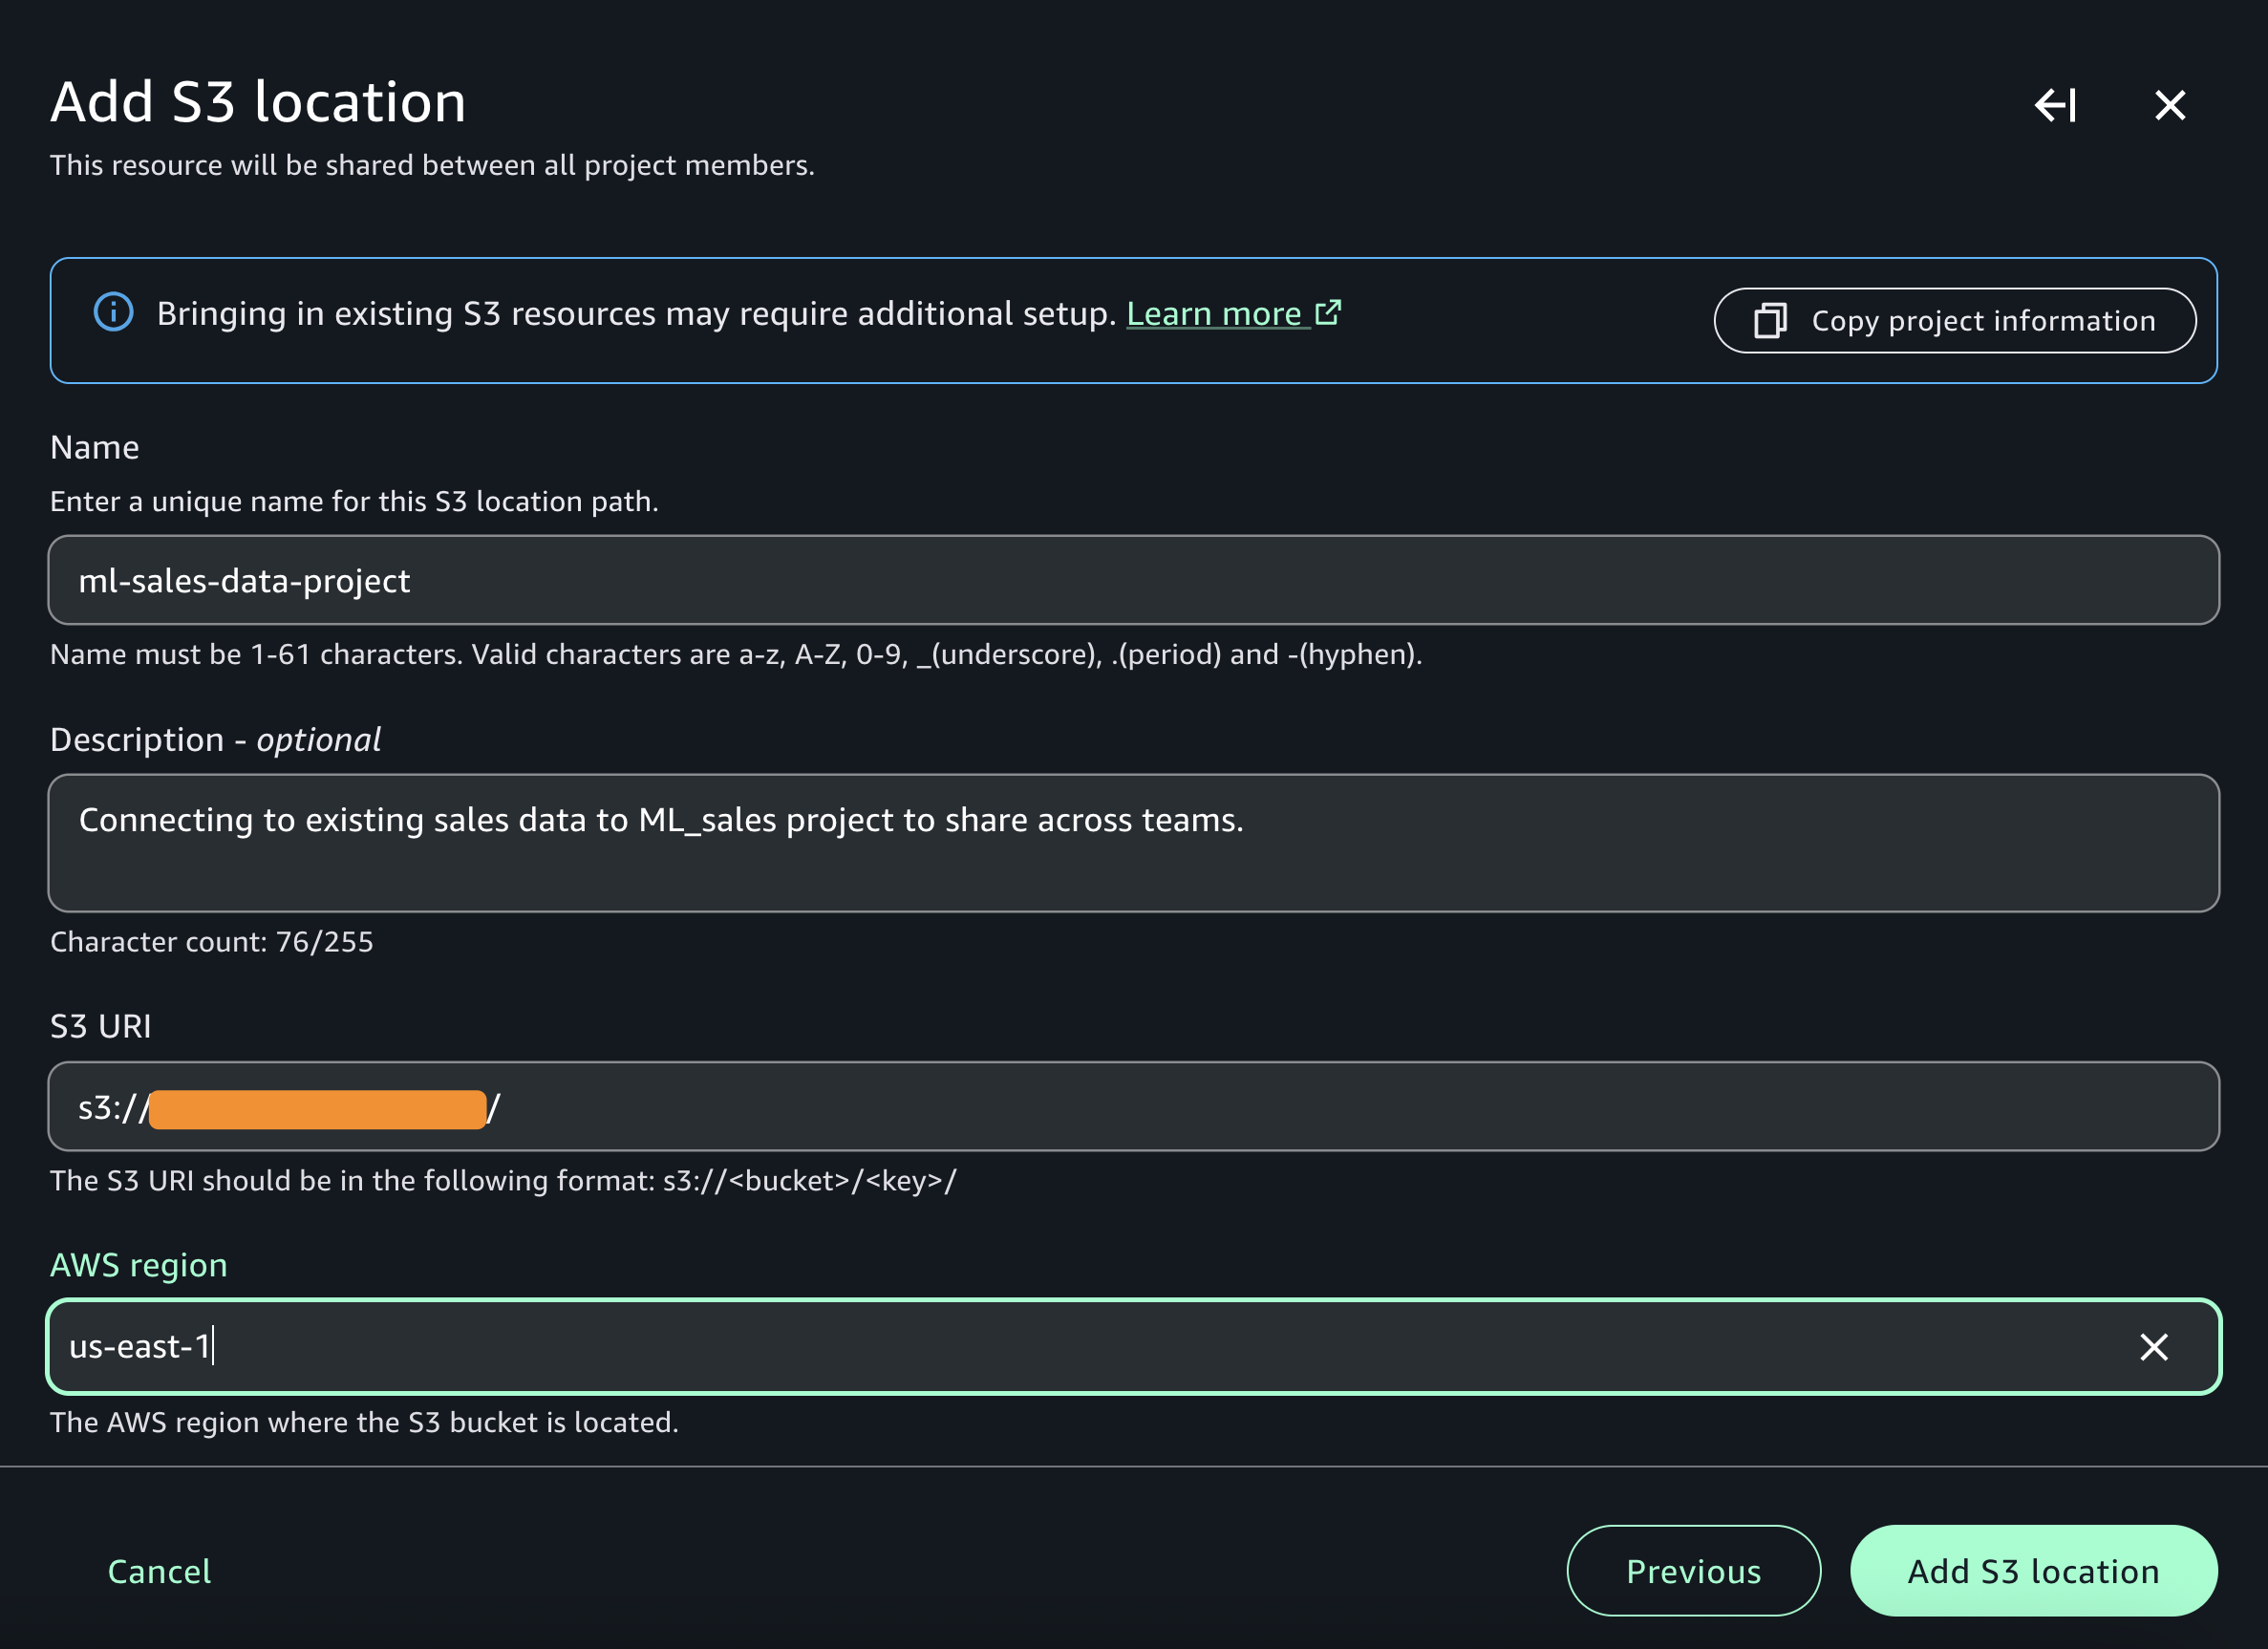
  1. On the Add S3 location page, enter the following details:
    1. Enter a name for the location path.
    2. (Optional) Add a description of the location path.
    3. Use the S3 URI and AWS Region provided by your admin.
    4. If your admin granted you access using an access role instead of the project role, enter the access role ARN obtained from your admin.
    5. Choose Add S3 location.

For more details, see Adding Amazon S3 data.

Publish data to SageMaker Catalog to make it discoverable

After you add the Amazon S3 location, complete the following steps to publish the data:

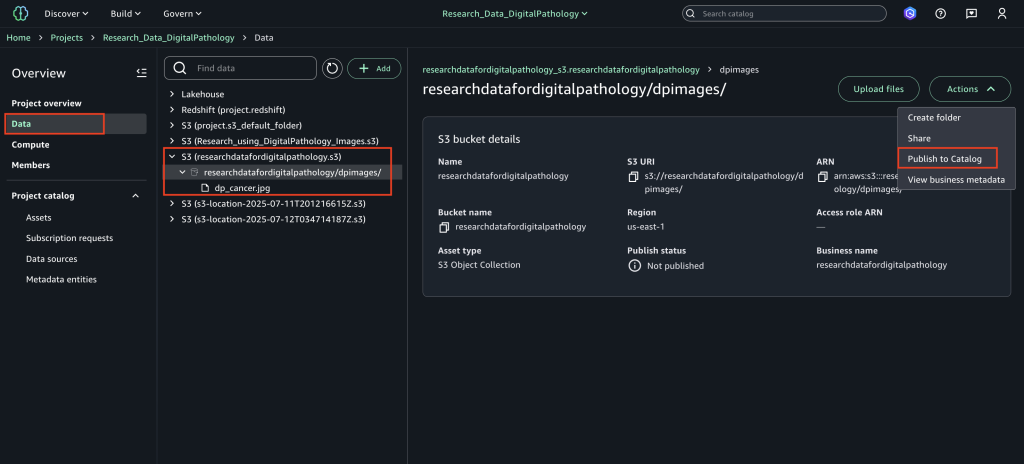
  1. In SageMaker Unified Studio, go to your project.
  2. Choose Data in the navigation pane and choose the Amazon S3 location.
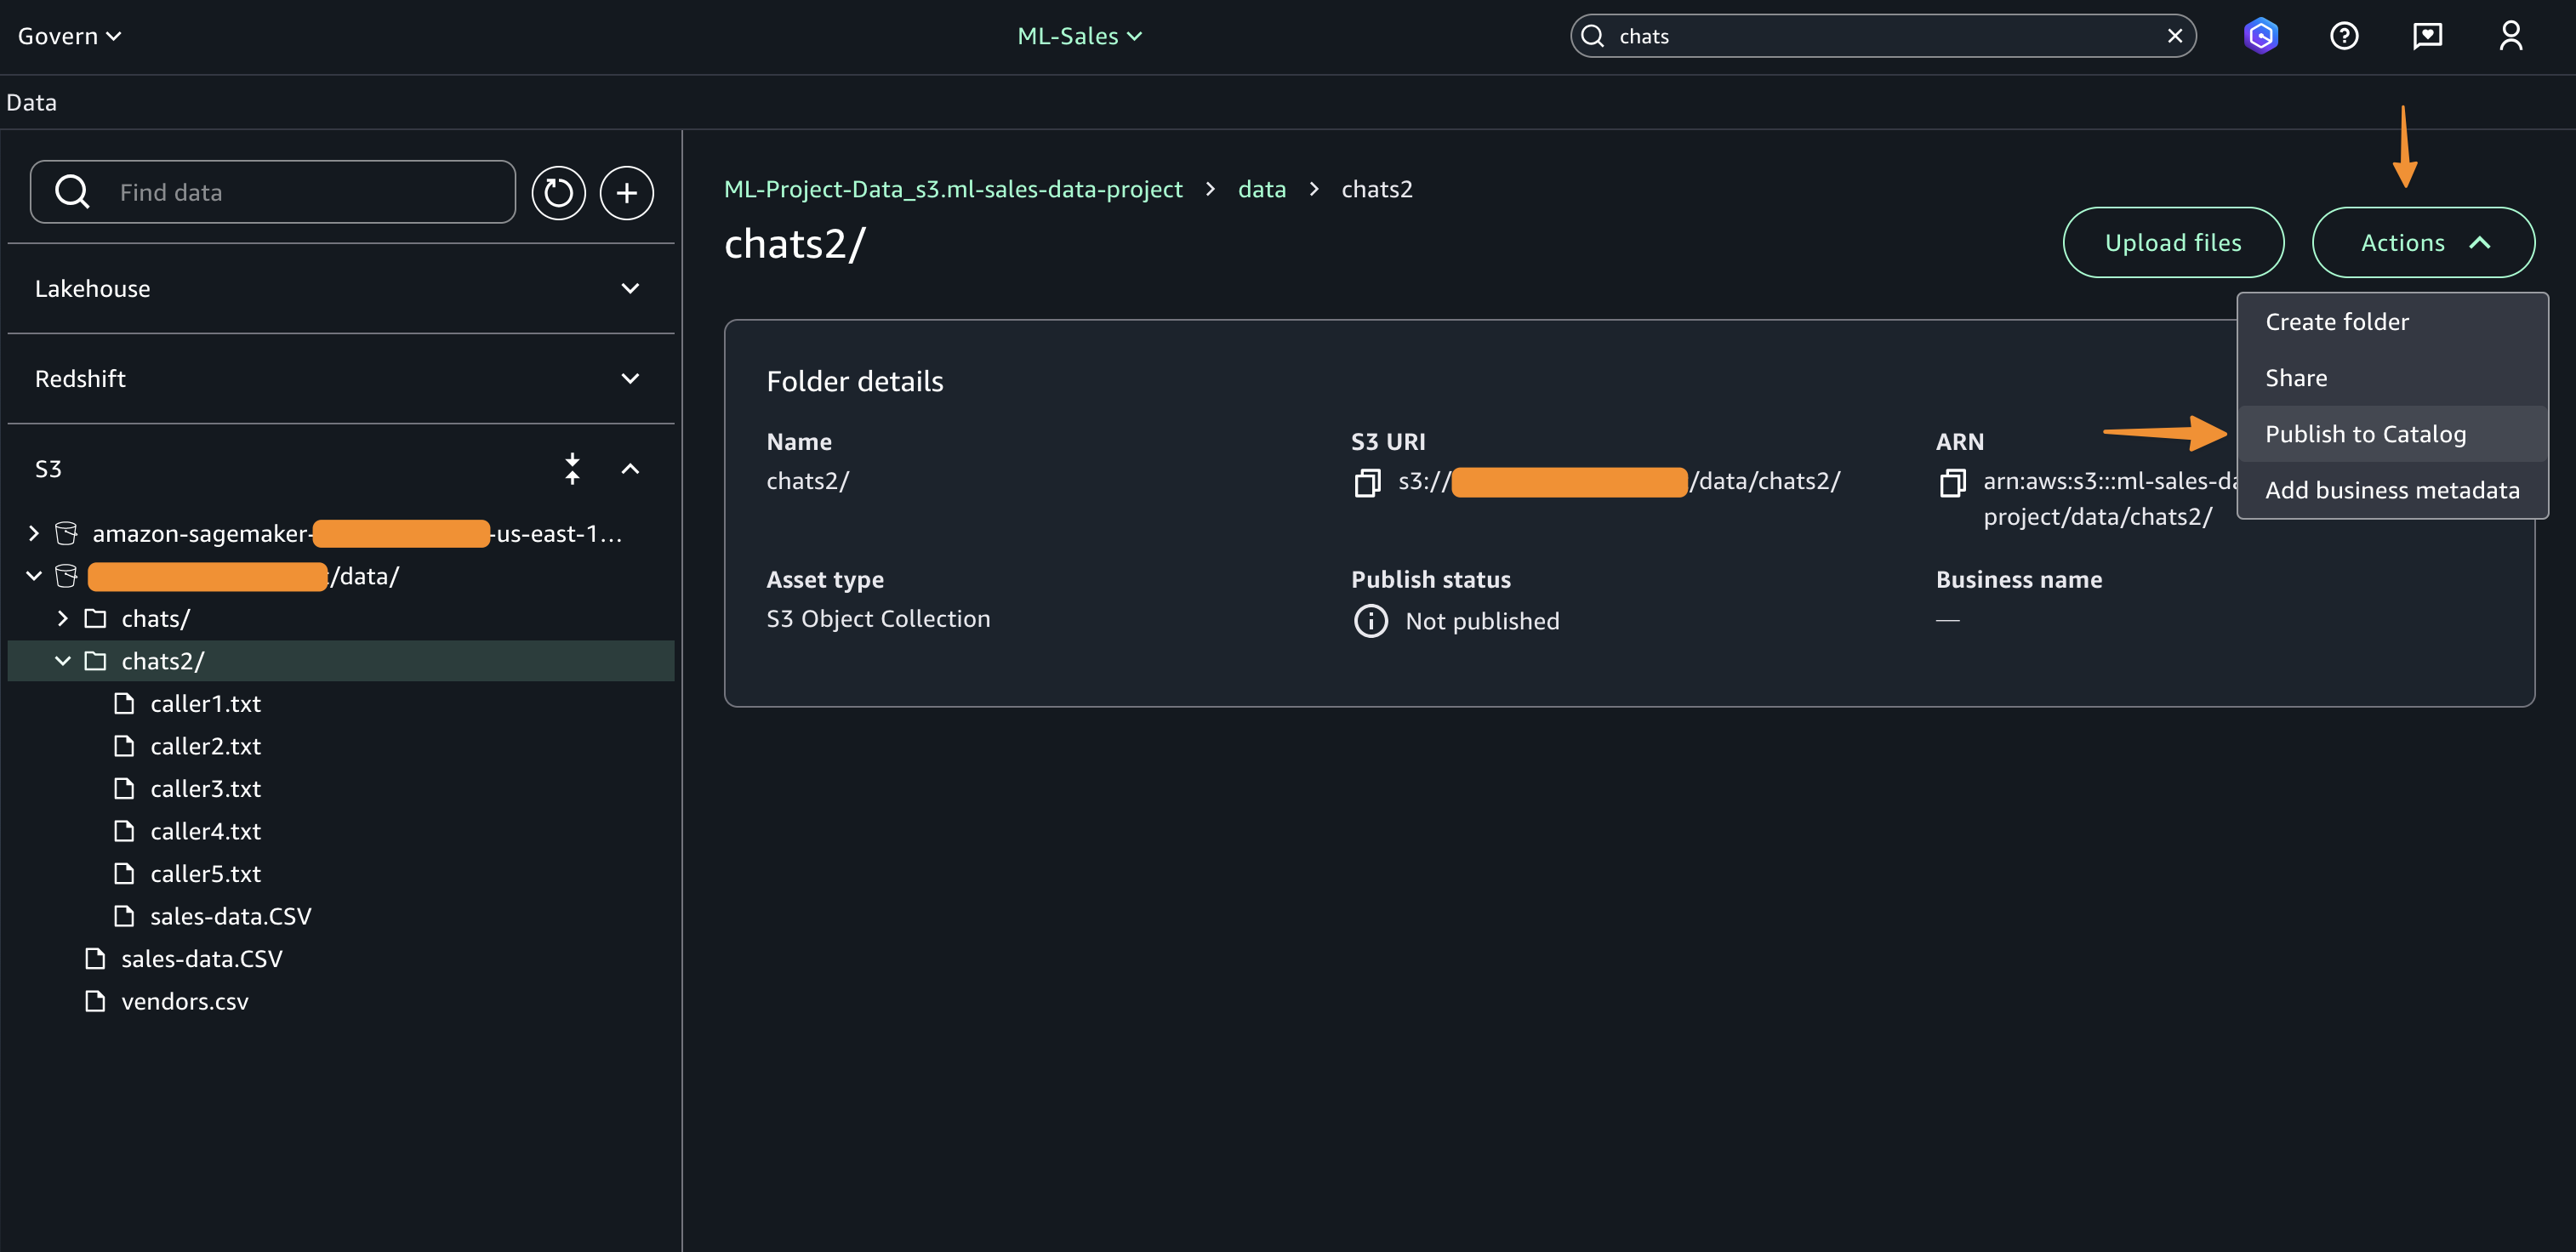
  3. On the Actions dropdown menu, choose Publish to Catalog.

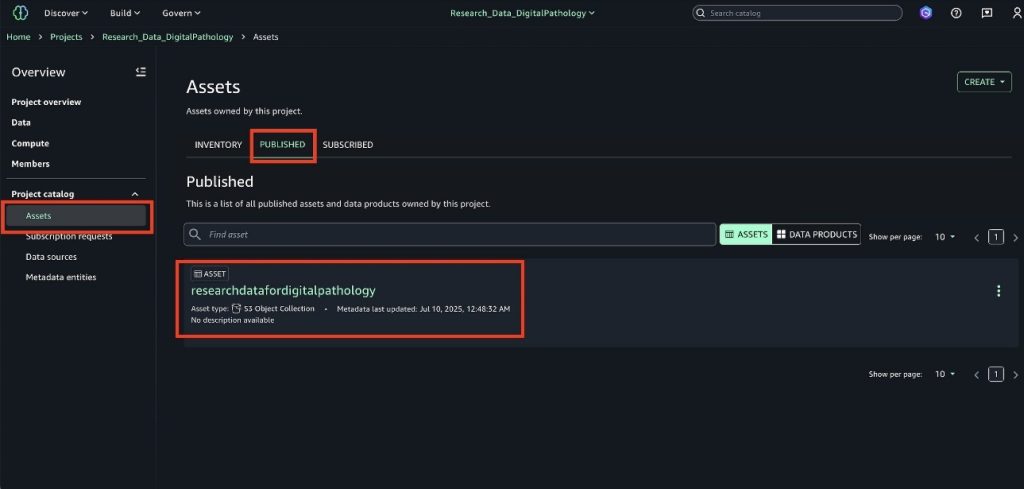
After you publish the assets, you can find the assets on the Published tab in the Assets page under Project catalog in the navigation pane.

Create a consumer project

Create a consumer project for researchers to collaborate and bring necessary assets for their analysis and add researchers as members to the project. Consumers can search for available (published) data assets on digital pathology images for cancer research and then subscribe to work with it using JupyterLab notebooks in SageMaker. For more details on how to create projects, refer to Create a project. For instructions to add members, refer to Add project members.

Find relevant assets and request access

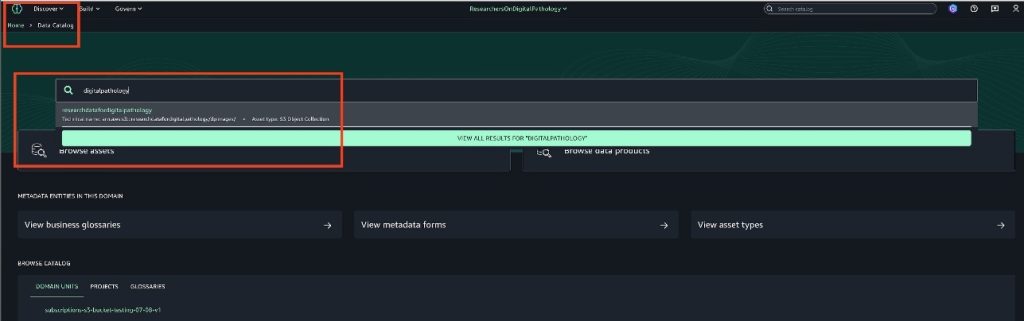
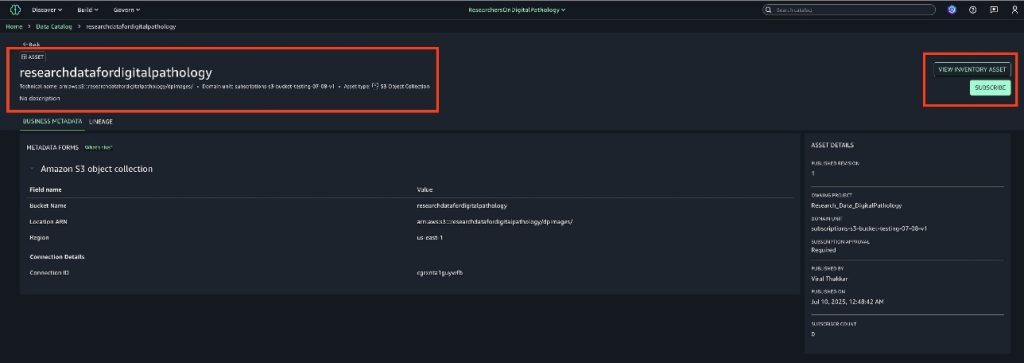
Researchers can search the SageMaker Catalog for available (published) data assets using the string digitalpathology. Complete the following steps:

  1. In SageMaker Unified Studio, on the Discover dropdown menu, choose Data Catalog.
  2. Find the asset you want to subscribe to by browsing or entering the name of the asset into the search bar.

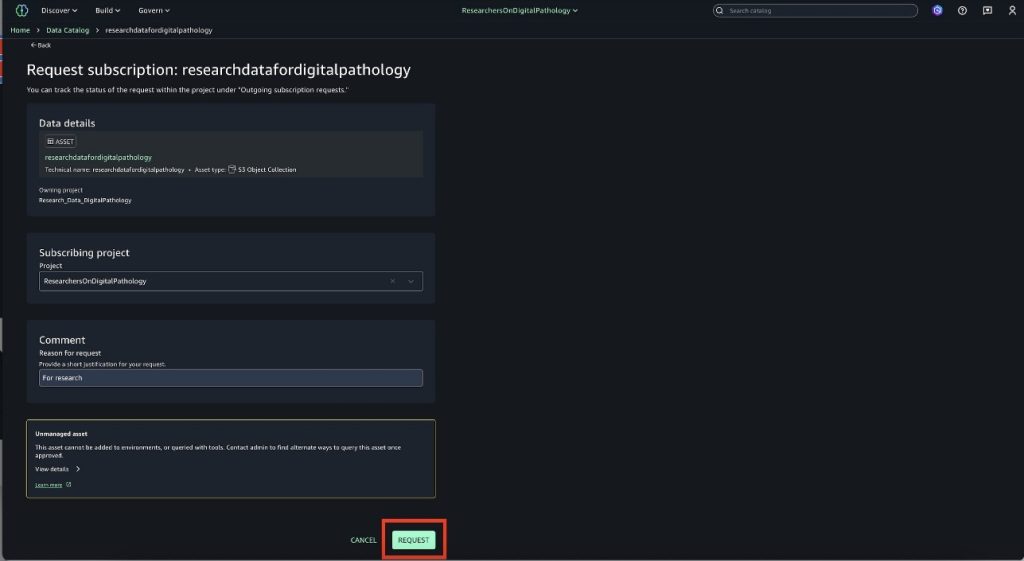
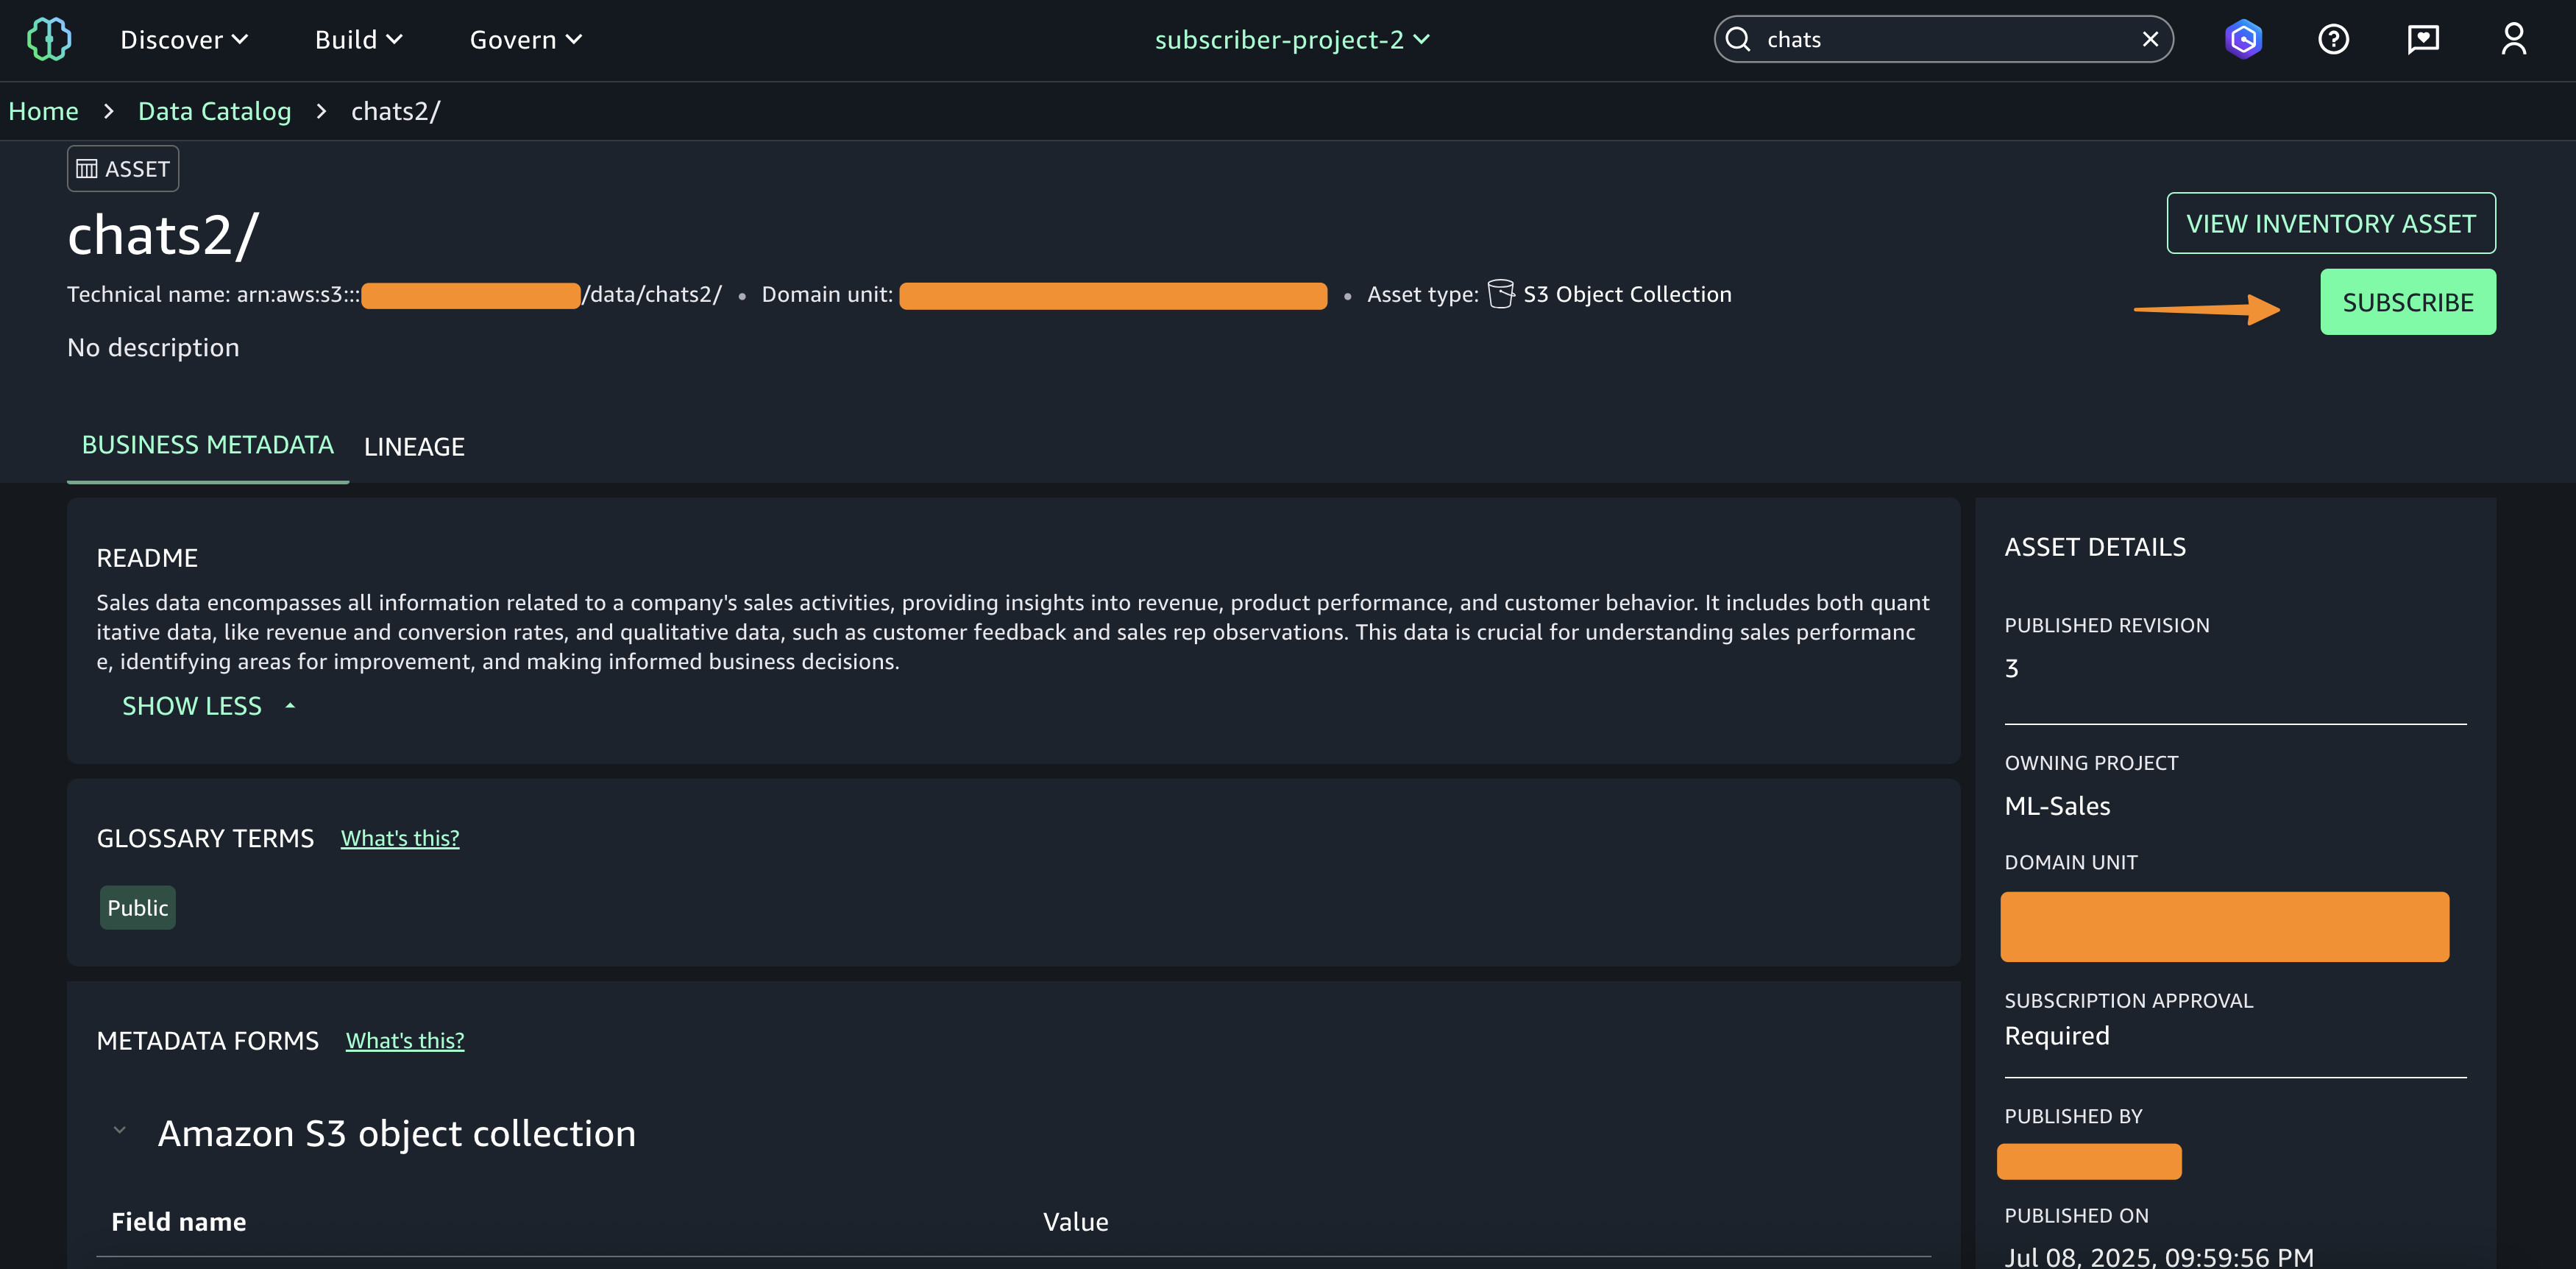
  1. Choose Subscribe.

  1. Provide the following information:
    1. The project to which you want to subscribe the asset.
    2. A short justification for your subscription request. This information is used by the data producer to validate the request to grant access.
  2. Choose Request.

After you’re approved, the project will be subscribed to the asset and access is granted automatically. To provide access, SageMaker Catalog uses S3 Access Grants to grant read permission to the subscribing project for the specific S3 bucket or prefix.

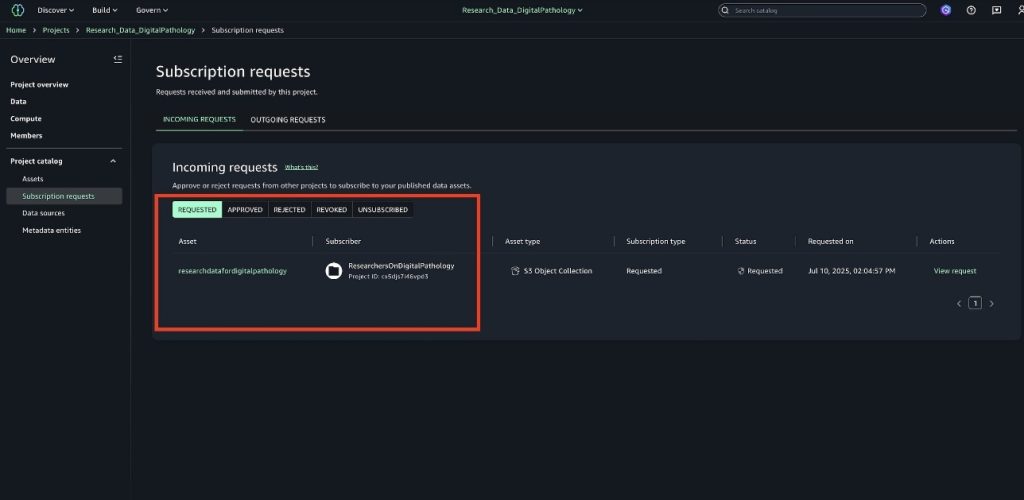
To view the status of the subscription request, go to the project with which you subscribed to the asset. Choose Subscription requests in the navigation pane, then choose the Outgoing requests tab. This page lists the assets to which the project has requested access. You can filter the list by the status of the request.

Review and approve the subscription request

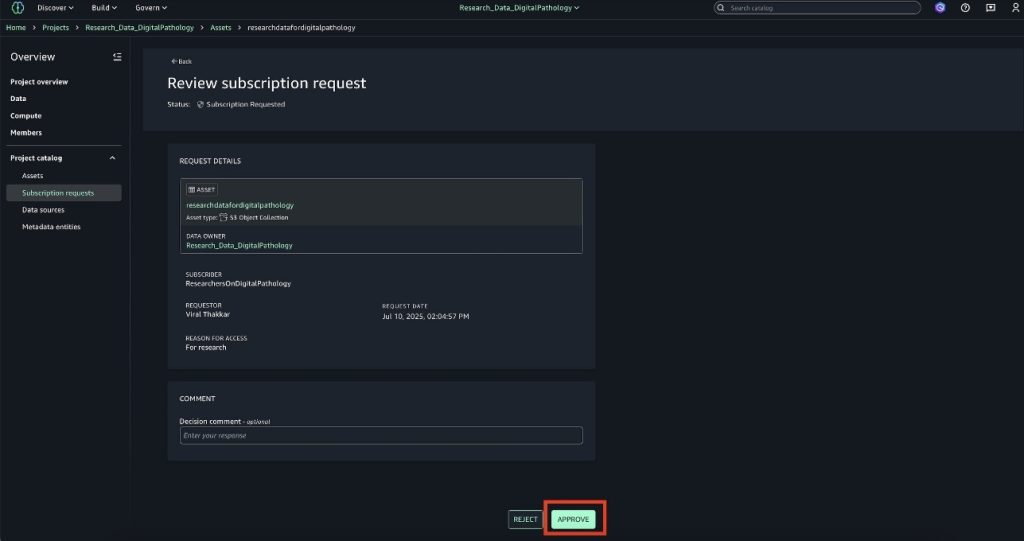
The data producer or engineer of the publishing project must receive the request from the researcher and approve the request. After the request is approved, the researcher will have access to the objects for the S3 bucket (or prefix).

Before approving, the data producer can view the details of the subscription request to make sure they know who will get access to the data they own.

After they approve the request, the data producers can audit the different requests they have for the assets they own.

Access the subscribed data in notebooks

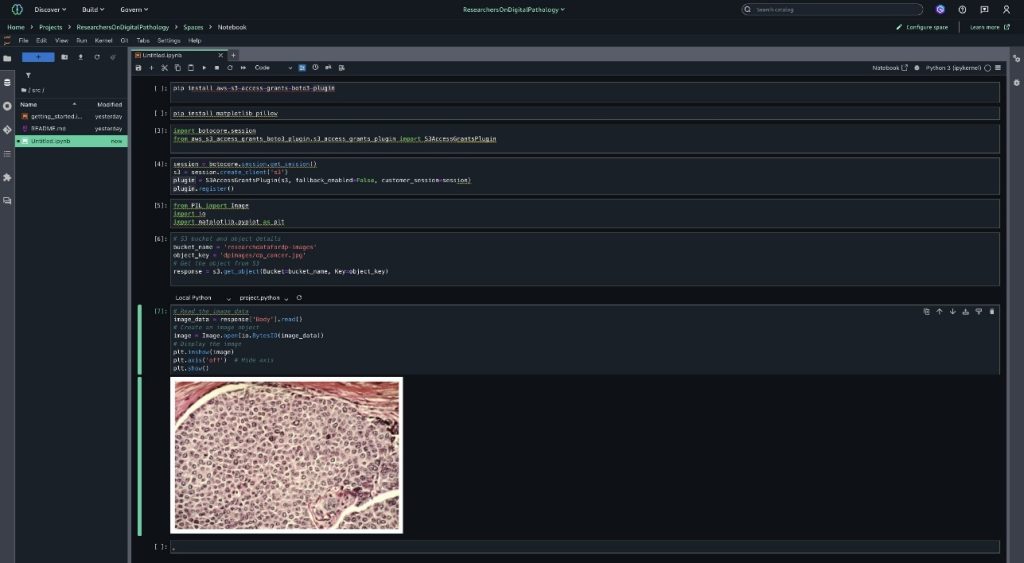
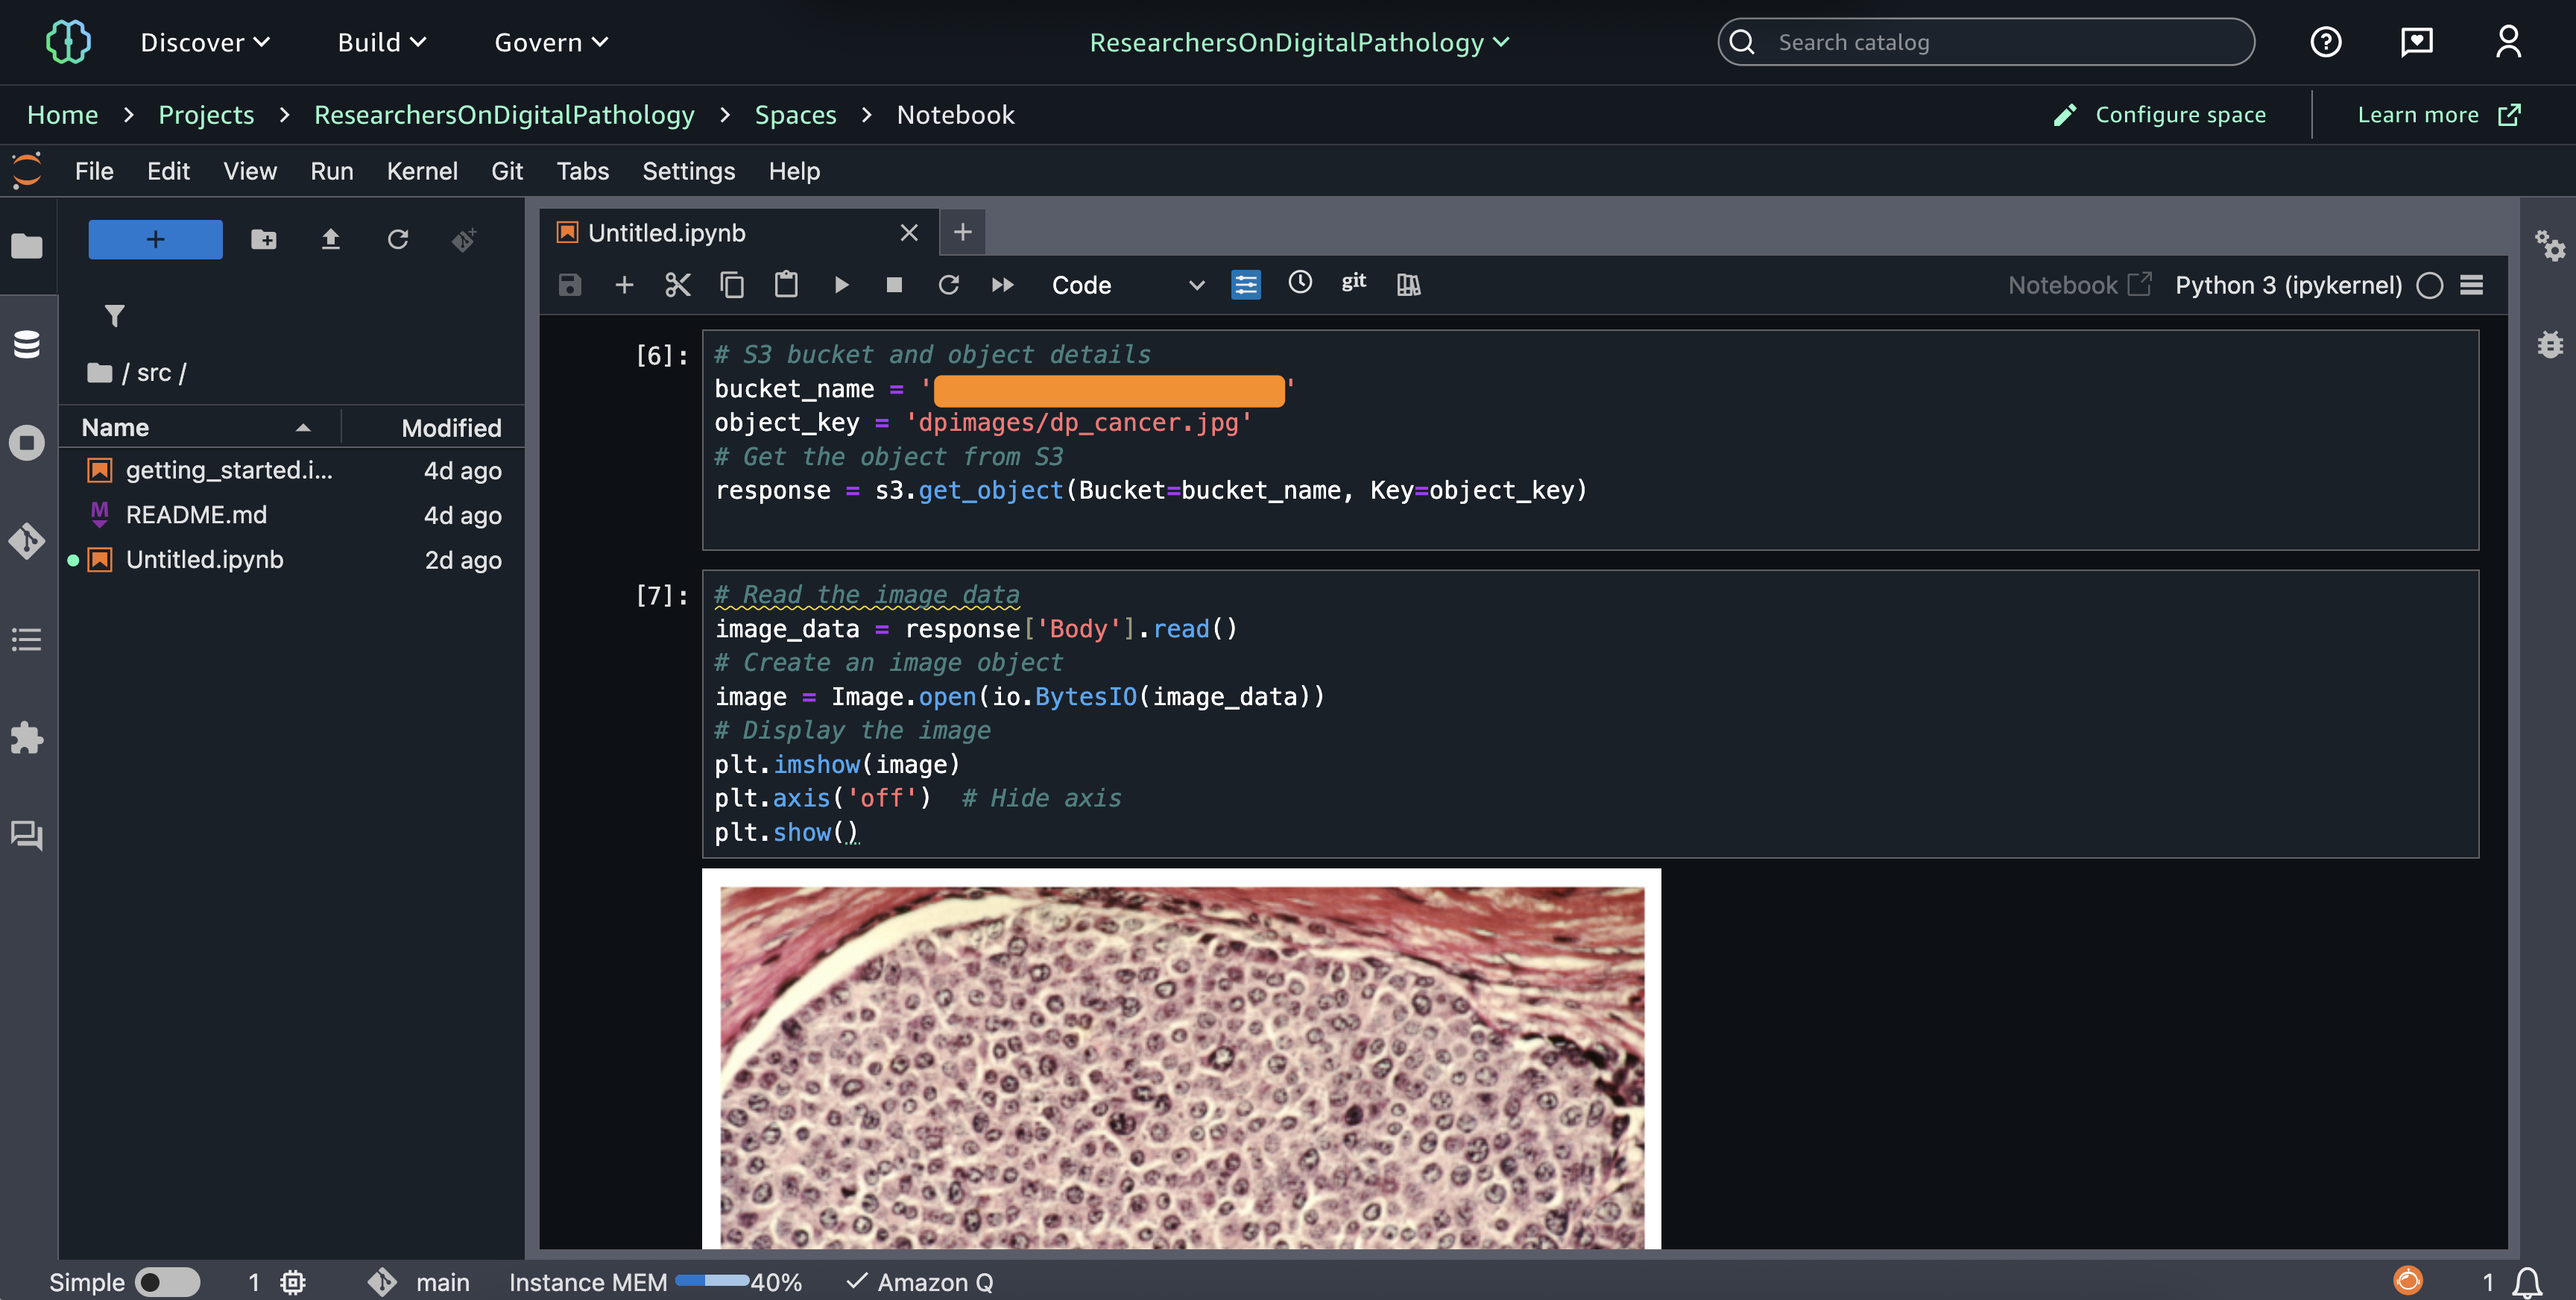
After the access request is approved, the researcher can open a JupyterLab notebook from SageMaker Unified Studio and access S3 objects to work on their research.To navigate to the JupyterLab notebook, complete the following steps:

  1. In SageMaker Unified Studio, open your project.
  2. On the Build dropdown menu, choose JupyterLab.

The following is sample Python code to access subscribed data. This sample code retrieves the S3 object that the researcher has been given access to and uses Matplotlib (a comprehensive 2D plotting library for Python language) to display the image in the notebook. In a real-world use case, a researcher typically uses these images for displaying or training machine learning models or performing multimodal analysis.

# Install necessary libraries
pip install aws-s3-access-grants-boto3-plugin
pip install matplotlib pillow

import botocore.session
from aws_s3_access_grants_boto3_plugin.s3_access_grants_plugin import S3AccessGrantsPlugin
session = botocore.session.get_session()
s3 = session.create_client('s3')
plugin = S3AccessGrantsPlugin(s3, fallback_enabled=False, customer_session=session)
plugin.register()

from PIL import Image
import io
import matplotlib.pyplot as plt


# S3 bucket and object details for digital pathology image
bucket_name = '[bucket name]'
object_key = '[prefix]/[object]'

# Get the image object from S3
response = s3.get_object(Bucket=bucket_name, Key=object_key)

# Read the image data
image_data = response['Body'].read()
# Create an image object
image = Image.open(io.BytesIO(image_data))

# Display the image
plt.imshow(image)
plt.axis('off') # Hide axis
plt.show()

SageMaker and S3 Access Grants integrations

The SageMaker Catalog integration with S3 Access Grants facilitates secure data access across Amazon EMR Serverless, AWS Glue, Amazon EMR on Amazon EC2, and JupyterLab notebooks through simple configuration settings. By enabling S3 Access Grants with two properties ('fs.s3.s3AccessGrants.enabled': 'true' and 'fs.s3.s3AccessGrants.fallbackToIAM': 'true'), users gain streamlined access control while maintaining IAM as a fallback option. These configurations are automated in SageMaker Unified Studio. To learn more about S3 Access Grants integrations, see S3 Access Grants integrations, and for Boto3 S3 Access Grants support, refer to the following GitHub repo.

Conclusion

In this post, we discussed the added support for S3 general purpose buckets in SageMaker, and how they can be cataloged in SageMaker Catalog to help users quickly discover and securely manage access when sharing with other teams.

To learn more about SageMaker and how to get started, refer to the Amazon SageMaker User Guide and Amazon S3 data in Amazon SageMaker Unified Studio.


About the authors

Priya Tiruthani is a Senior Technical Product Manager with Amazon DataZone at AWS. She focuses on improving data discovery and curation required for data analytics. She is passionate about building innovative products to simplify customers’ end-to-end data journey, especially around data governance and analytics. Outside of work, she enjoys being outdoors to hike, capture nature’s beauty, and recently play pickleball.

Subrat Das is a Principal Solutions Architect and part of the Global Healthcare and Life Sciences industry division at AWS. He is passionate about modernizing and architecting complex customer workloads. When he’s not working on technology solutions, he enjoys long hikes and traveling around the world.

Santhosh Padmanabhan is a Software Development Manager at AWS, leading the Amazon SageMaker Catalog engineering team. His team designs, builds, and operates services specializing in data, machine learning, and AI governance. With deep expertise in building distributed data systems at scale, Santhosh plays a key role in advancing AWS’s data governance capabilities.

Yuhang Huang is a Software Development Manager on the Amazon SageMaker Unified Studio team. He leads the engineering team to design, build, and operate scheduling and orchestration capabilities in SageMaker Unified Studio. In his free time, he enjoys playing tennis.

Guide to adopting Amazon SageMaker Unified Studio from ATPCO’s Journey

Post Syndicated from Mitesh Patel original https://aws.amazon.com/blogs/big-data/guide-to-adopting-amazon-sagemaker-unified-studio-from-atpcos-journey/

This blog post is co-written with Raj Samineni from ATPCO.

Launched at AWS re:Invent 2024, the next generation of Amazon SageMaker is expediting innovation for organizations such as ATPCO through a unified data management and tooling experience for analytics and AI use cases. This comprehensive service provides both technical and business users with Amazon SageMaker Unified Studio, a single data and AI development environment to discover the data and put it to work using familiar AWS tools. SageMaker Unified Studio offers a single governed environment to complete end-to-end development workflows, including data analysis, data processing, model training, generative AI application building, and more. It simplifies the creation of analytics and AI applications, fast-tracking the journey from raw data to actionable insights through its integrated data and tooling environment.

ATPCO is the backbone of modern airline retailing, helping airlines and third-party channels deliver the right offers to customers at the right time. ATPCO’s vision is to be the platform driving innovation in airline retailing while remaining a trusted partner to the airline ecosystem. ATPCO aims to support data-driven decision-making by making high-quality data discoverable by every business unit, with the appropriate governance on who can access what, and required tooling to support their needs. ATPCO addressed data governance challenges using Amazon DataZone. SageMaker Unified Studio, built on the same architecture as Amazon DataZone, offers additional capabilities, so users can complete various tasks such as building data pipelines using AWS Glue and Amazon EMR, or conducting analyses using Amazon Athena and Amazon Redshift query editor across diverse datasets, all within a single, unified environment.

In this post, we walk you through the challenges ATPCO addresses for their business using SageMaker Unified Studio. We start with the admin flow, a one-time setup process that lays the foundation for non-admin users in preparation for a company-wide rollout. When onboarding users from different business units to SageMaker Unified Studio, it’s crucial to make sure they have immediate access to their data sources such as Amazon Simple Storage Service (Amazon S3), AWS Glue Data Catalog, and Redshift tables as well as tools like Amazon EMR, AWS Glue, and Amazon Redshift that they already use. This helps users become productive swiftly and use the full potential of SageMaker Unified Studio. Next, we walk you through the developer flow, detailing how non-admin users can use SageMaker Unified Studio to access their data and act on it using their choice of tools.

“SageMaker Unified Studio has transformed how our teams access and collaborate on data. It’s the first time business and technical users can work together in a single, intuitive environment—no more tool switching or fragmented workflows.”
–Rajesh Samineni, Director of Data Engineering at ATPCO

ATPCO’s challenges

The implementation of SageMaker Unified Studio at ATPCO has been instrumental in addressing several critical challenges and unlocking new use cases across various business units within the organization. By building on the foundation laid by Amazon DataZone, ATPCO is helping users self-serve insights and fostering a culture of shared understanding and reusability of data assets, leading to more informed decision-making and a robust data culture.

SageMaker Unified Studio helped address the following challenges:

  • Data silos and discoverability – Analysts often struggled to locate the right data sources, verify data freshness, and maintain consistent definitions across different departments. By offering a single entry point for searching and subscribing to curated datasets, SageMaker Unified Studio minimizes these barriers. Integrated tools for data exploration, querying, and visualization, along with contextual metadata and lineage, builds trust in the data, making it straightforward for users to find and use the information they need.
  • Manual data handling – Teams relied heavily on manual exports and custom reports to gather insights, leading to inefficiencies and delays in decision-making. SageMaker Unified Studio helps users across departments, including product, sales, operations, and analytics, self-serve insights without manual intervention. This accelerates the decision-making process and helps teams focus on strategic initiatives rather than data collection.

Solution overview

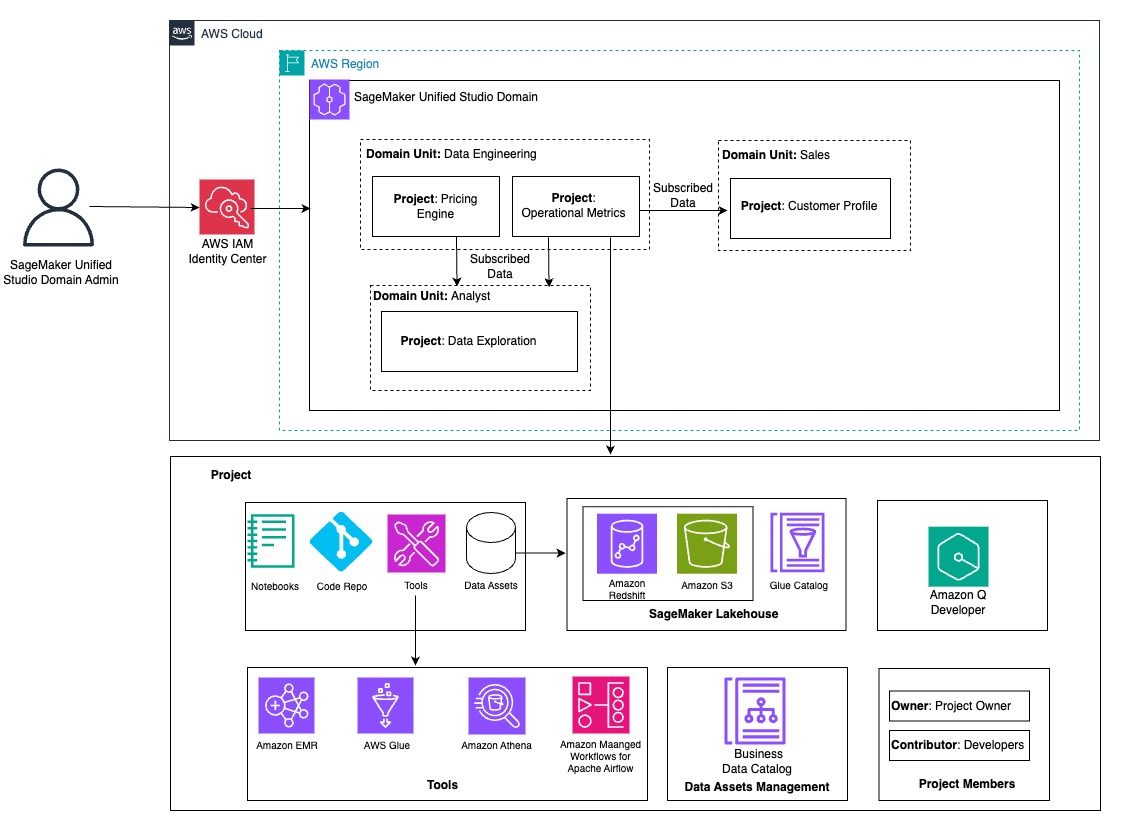
The following diagram illustrates ATPCO’s architecture for SageMaker Unified Studio.

ATPCO-Solution-SMUS-AdminFlow-1

The following sections walk you through the steps that ATPCO went through to prepare the SageMaker Unified Studio environment for use by different personas in engineering and business units.

Prerequisites

If you’re new to SageMaker Unified Studio, you should first become familiar with concepts such as domains, domain units, projects, project profiles, blueprints, lakehouses, and catalogs before continuing with this post. For a company-wide rollout of SageMaker Unified Studio, it’s important to understand the foundation setup required as an admin user. For more information about the role of a SageMaker Unified Studio admin user and steps required to set up a SageMaker Unified Studio domain,refer to Foundational blocks of Amazon SageMaker Unified Studio: An admin’s guide to implement unified access to all your data, analytics, andAI. As an admin user, start with domain units and projects based on the need of different business units for the data and tooling.

Create domain units and set up projects with required tools

As an admin or root domain owner, you begin with the design of domain units and projects to organize different teams and users to their respective domain units. When non-admin users log in to the SageMaker Unified Studio portal, they should have seamless access to necessary AWS resources. These resources include the required tools and data sources to perform their job. Providing users access to these resources is critical for the successful adoption and utilization of SageMaker Unified Studio in your organization. ATPCO created separate domain units for engineering teams and non-engineering business units, as shown in the preceding architecture diagram. It only shows few examples. In reality, they have more domain units to meet their business needs, which we discuss in the following sections.

Data engineering domain

This domain unit has the Operational Metrics project, managed by the data engineering team, which supports a key backbone of visibility across the organization: understanding how ATPCO’s products perform in real time. Data engineers bring together signals from infrastructure, application logs, API monitoring, and internal systems to build aggregated, curated datasets that track latency, availability, adoption, and reliability. These operational metrics are published using SageMaker Unified Studio for consumption by other domains. Rather than fielding one-off requests or maintaining bespoke dashboards for different stakeholders, the engineering team now:

  • Builds reusable data assets that can be subscribed to one time and reused by many
  • Creates unified views of system health that are automatically updated and versioned
  • Supports other teams such as Product, Sales, and analysts with quick access to performance indicators in a format aligned with their needs

SageMaker Unified Studio becomes the center for operational intelligence, reducing duplication and making sure data engineers can focus on scale and automation rather than ticket-based support.

Analyst domain

The Data Exploration project in this domain unit serves the entire ATPCO community. Its purpose is to make available datasets regardless of their owning domain easily discoverable and ready for analysis. Previously, analysts struggled with locating the right data source, verifying its freshness, or aligning on consistent definitions. With SageMaker Unified Studio, those barriers are removed. The project provides:

  • A single entry point where users can search and subscribe to curated datasets
  • Integrated tools for exploration, query, and visualization
  • Contextual metadata and lineage to build trust in the data

Users in product, strategy, operations, or analytics can self-serve insights without waiting on manual exports or custom reports.

Sales domain

The Customer Profile project in this domain unit helps the Sales team understand which customers are actively engaging with ATPCO’s products, how they are using them, and where there might be opportunities to strengthen relationships. By using SageMaker Unified Studio, Sales team members can access the following:

  • Customer data sourced from CRM systems, including interaction history, product adoption, and support engagement
  • Operational metrics from the Data Engineering team, revealing which features are being used, how often, and whether the customer is experiencing reliability issues

With this combined insight, the Sales team can accomplish the following:

  • Identify high-value accounts for follow-up based on recent usage
  • Detect drop-off in engagement or technical issues before a customer raises a concern
  • Tailor outreach and proposals using objective data, not assumptions

All of this happens within SageMaker Unified Studio, reducing the time spent on manual data gathering and enabling more strategic, proactive customer engagement.

Onboard data sources to domain units and projects

Now that domain units and projects are created for different business units, the next step is to onboard existing Amazon S3 data sources, Data Catalog tables, and database tables available in Amazon Redshift. After logging in, users have access to the required data and tools. This required the ATPCO team to build the inventory to see which team has access to what data sources and what level of permissions are needed. For example, the Data Engineering team needs access to raw, processed and curated S3 buckets for building data processing jobs. They must also read and write to the Data Catalog, and prepare and write curated and aggregated data to the Redshift tables. The following sections guide you through configuring these various data sources within SageMaker Unified Studio, making sure users can access the data sources to continue their work in SageMaker Unified Studio.

Configure existing Amazon S3 data sources into SageMaker Unified Studio

To use an existing S3 bucket in SageMaker Unified Studio, configure an S3 bucket policy that allows the appropriate actions for the project AWS Identity and Access Management (IAM) role.

The Data Engineering team that owns the data processing pipeline must grant access to raw, processed, and curated S3 buckets to the data engineering project role. To learn more about using existing S3 buckets, refer to Access your existing data and resources through Amazon SageMaker Unified Studio, Part 2: Amazon S3, Amazon RDS, Amazon DynamoDB, and Amazon EMR.

Configure an existing Data Catalog into SageMaker Unified Studio

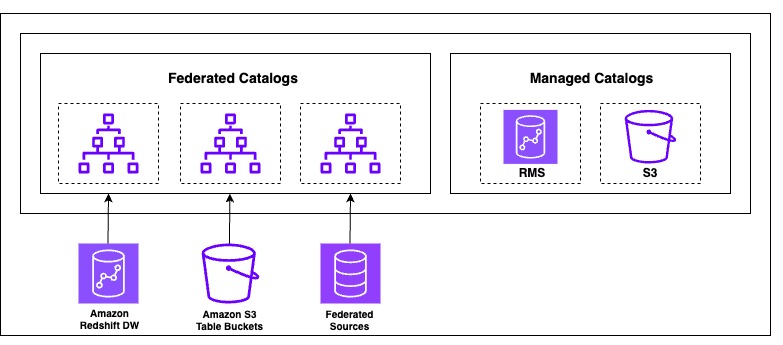
The next generation of SageMaker is built on a lakehouse architecture, which streamlines cataloging and managing permissions on data from multiple sources. Built on the Data Catalog and AWS Lake Formation, it organizes data through catalogs that can be accessed through an open, Apache Iceberg REST API to help enforce secure access to data with consistent, fine-grained access controls. SageMaker Lakehouse organizes data access through two types of catalogs: federated catalogs andmanaged catalogs (shown in the following figure). A catalog is a logical container that organizes objects from a data store, such as schemas, tables, views, or materialized views from Amazon Redshift. The following diagram illustrates this architecture.

ATPCO-Solution-SMUS-Catalog-2

ATPCO built a data lake on Amazon S3 using the Data Catalog and implemented data governance and fine-grained access control using Lake Formation. When developer users log in to SageMaker Unified Studio, they need access to the Data Catalog tables owned by their respective team. Existing Data Catalog databases are made available in SageMaker Lakehouse as a federated catalog because they’re created outside of SageMaker Lakehouse and not managed by it.

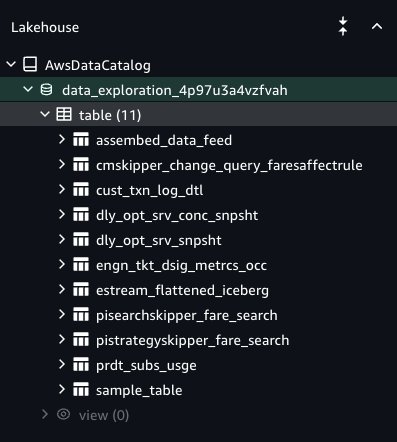
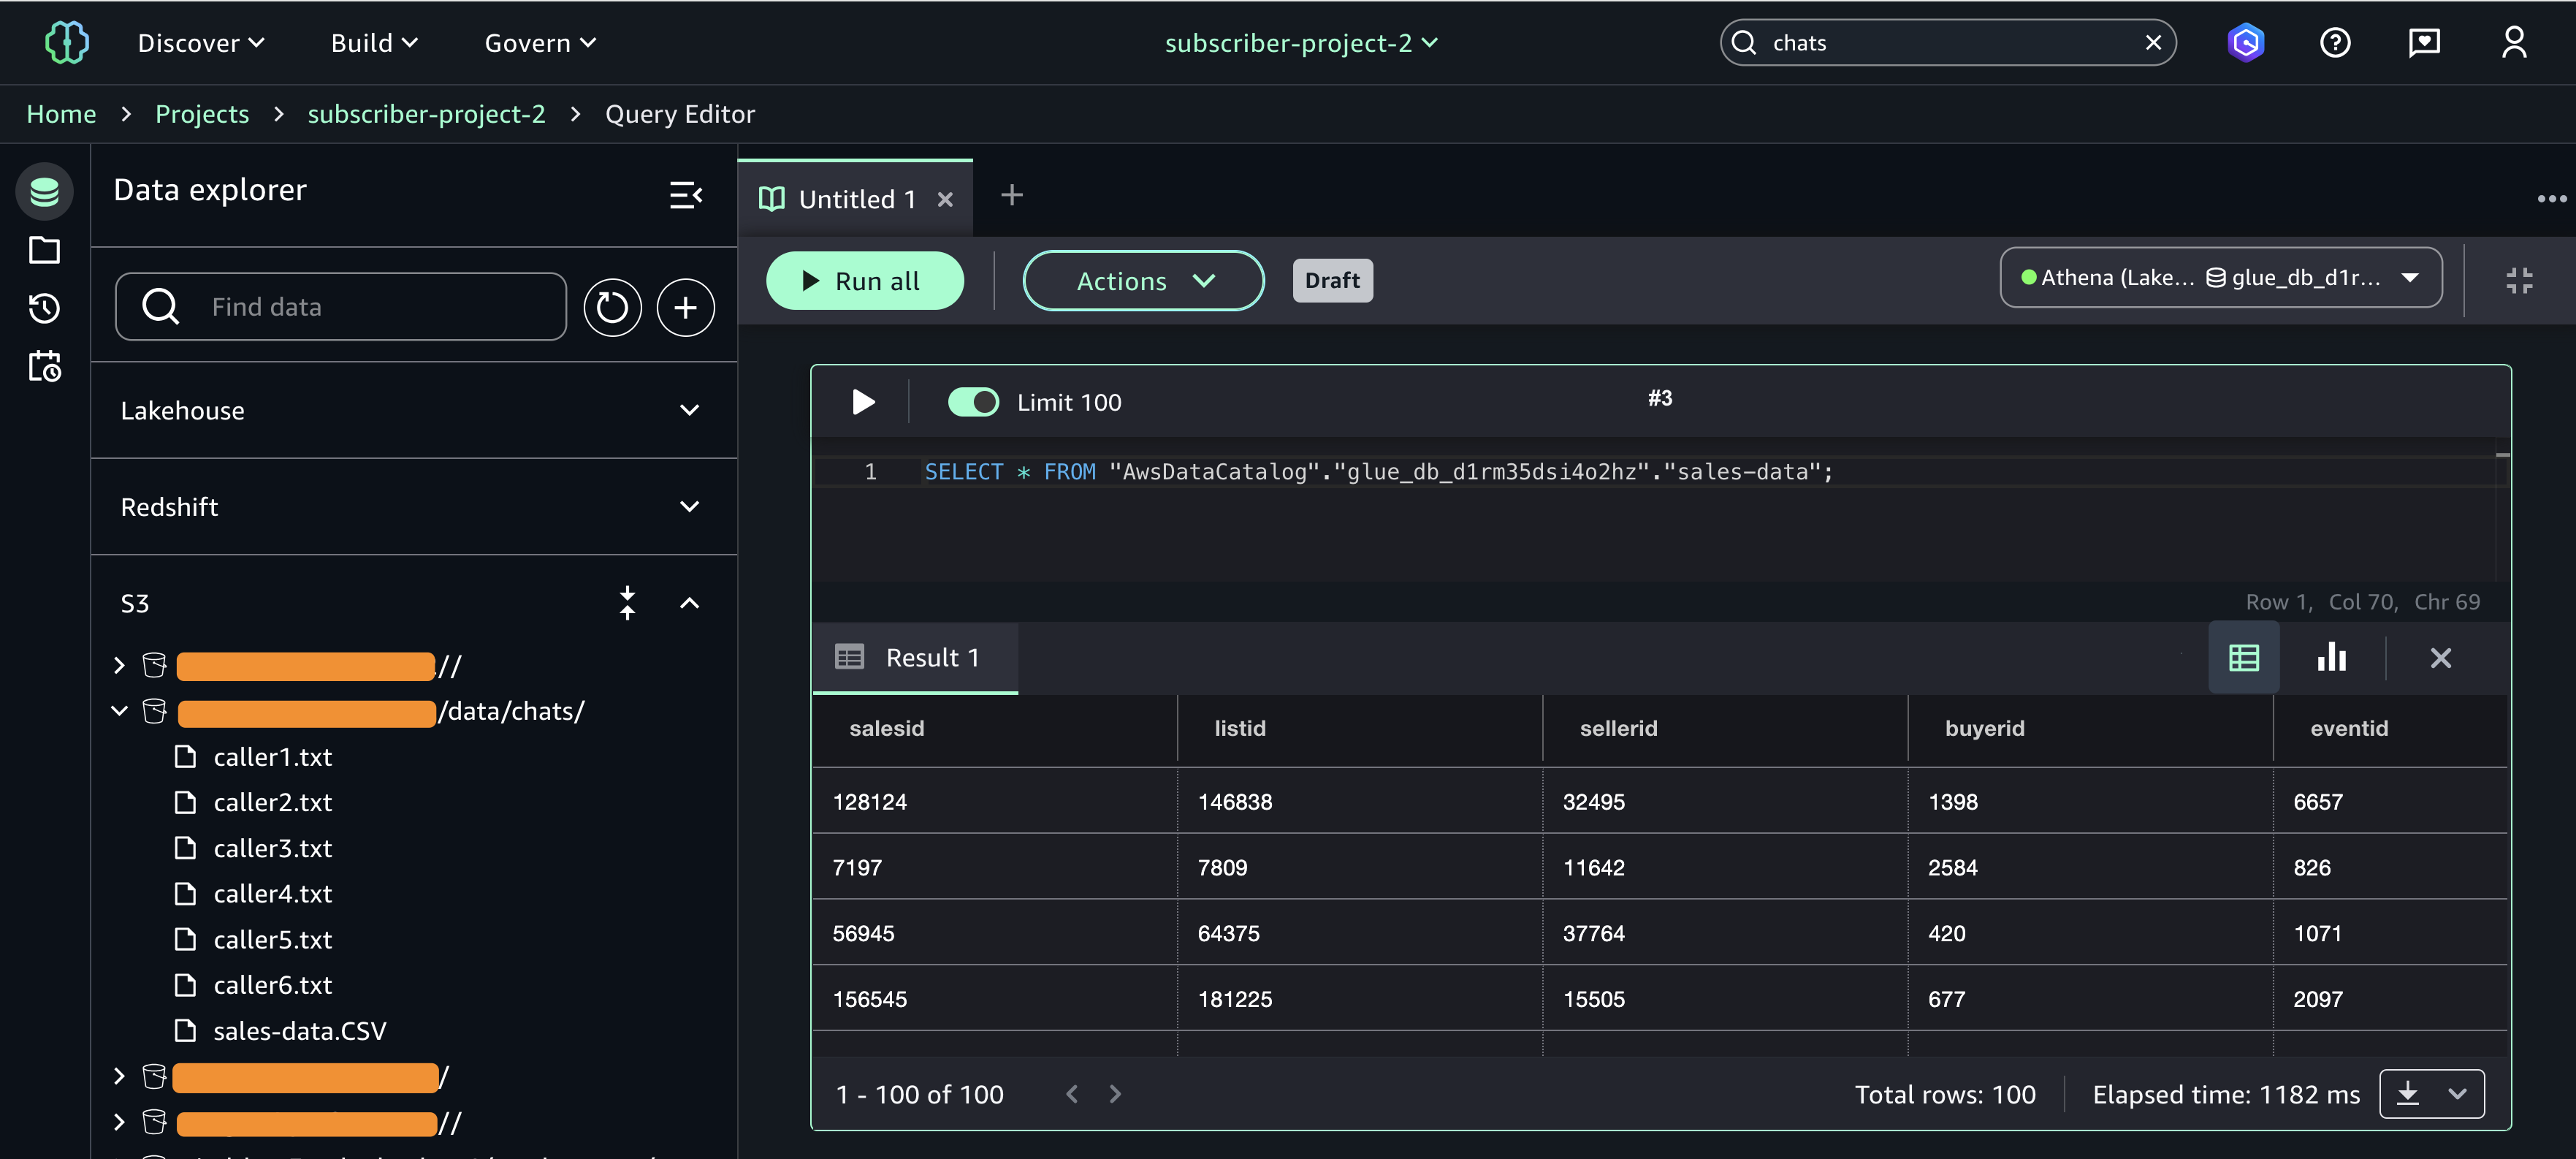
To access an existing Data Catalog, you must provide explicit permissions to SageMaker Unified Studio to be able to access the Data Catalog databases and tables. For more details, see Configure Lake Formation permissions for Amazon SageMaker Unified Studio. To onboard Data Catalog tables to SageMaker Lakehouse in SageMaker Unified Studio, the Lake Formation admin must grant access to specific Data Catalog database tables to the SageMaker Unified Studio project role. For more details, refer to Access your existing data and resources through Amazon SageMaker Unified Studio, Part 1: AWS Glue Data Catalog and Amazon Redshift. The Lake Formation permission model is the prerequisite to grant access to SageMaker Unified Studio. If Lake Formation is not the permission model for the Data Catalog, then you must register the S3 path and delegate the permission model to Lake Formation before it can be granted to the SageMaker Unified Studio project role. After you complete these steps, users of the project can access the Data Catalog database and are granted tables under the AwsDataCatalog namespace, and your tables will be visible in the Data Explorer (see the following screenshot). Your data is now ready for tagging, searching, enrichment, and data analysis.

ATPCO-Solution-SMUS-Catalog-2

Configure Redshift data into SageMaker Unified Studio

ATPCO relies on Amazon Redshift as their enterprise data warehouse and stores their aggregated data for insights and dashboarding. Users can combine the data from Amazon Redshift and SageMaker Lakehouse for unified data analysis in SageMaker Unified Studio without leaving SageMaker Unified Studio. For more information about how to add existing Redshift data sources, refer to Access your existing data and resources through Amazon SageMaker Unified Studio, Part 1: AWS Glue Data Catalog and Amazon Redshift.

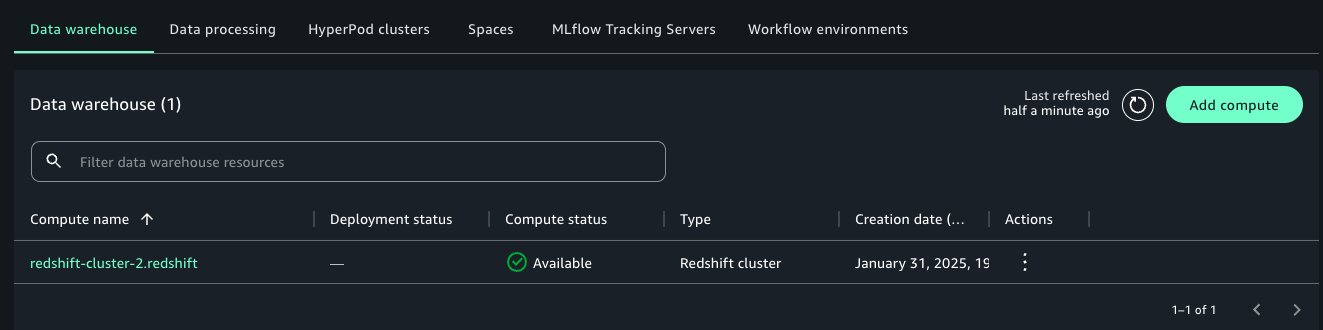
After it’s connected, the Amazon Redshift compute engine becomes visible in the Data Explorer of your project. Project users can perform the following actions:

  • Write and run SQL queries directly against Amazon Redshift
  • Explore Redshift schemas and tables
  • Use Redshift tables to define SageMaker Unified Studio data sources
  • Combine Redshift data with metadata tagging, glossary linking, and publishing

ATPCO-Solution-SMUS-Compute-4

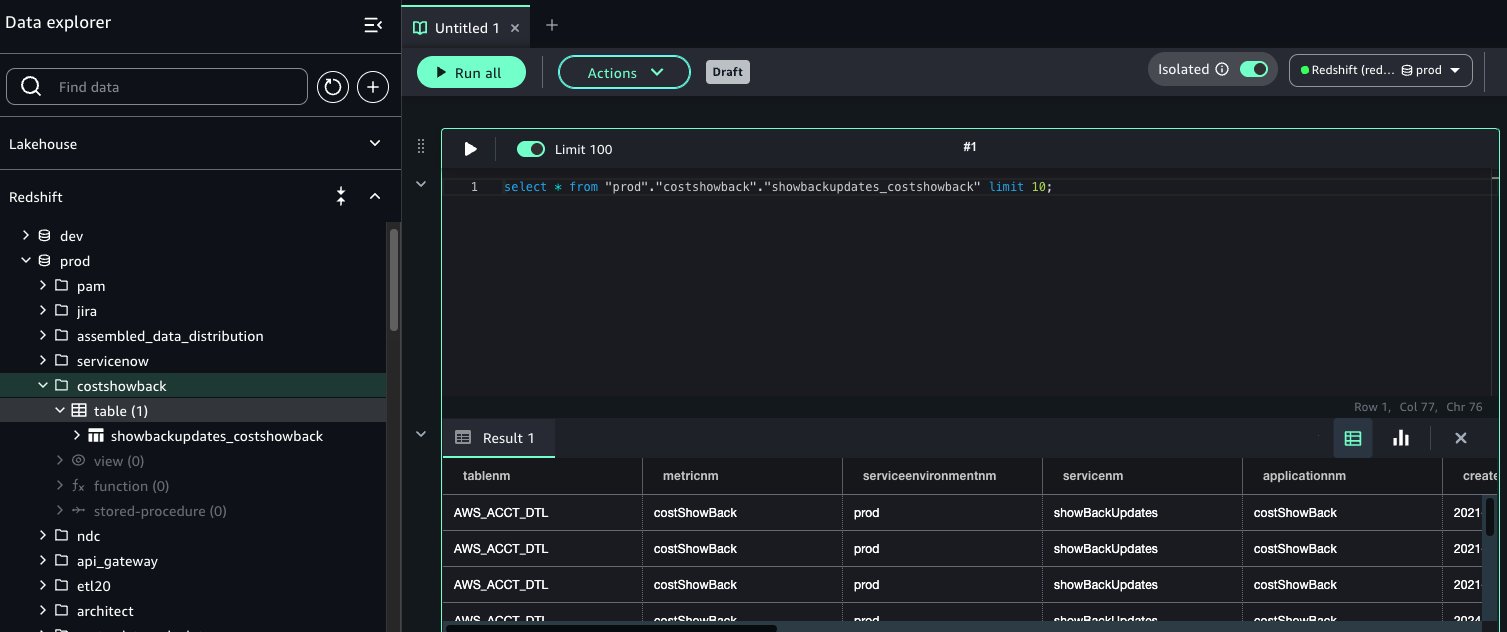
This doesn’t require copying or duplicating data. You’re using the data exactly where it lives in your Redshift cluster while benefiting from the collaborative features of SageMaker Unified Studio. Adding compute makes the data within the warehouse available to query inside the SageMaker Unified Studio query editor.

ATPCO-Solution-SMUS-DataExplore-5

Onboard users to their respective domain units and projects

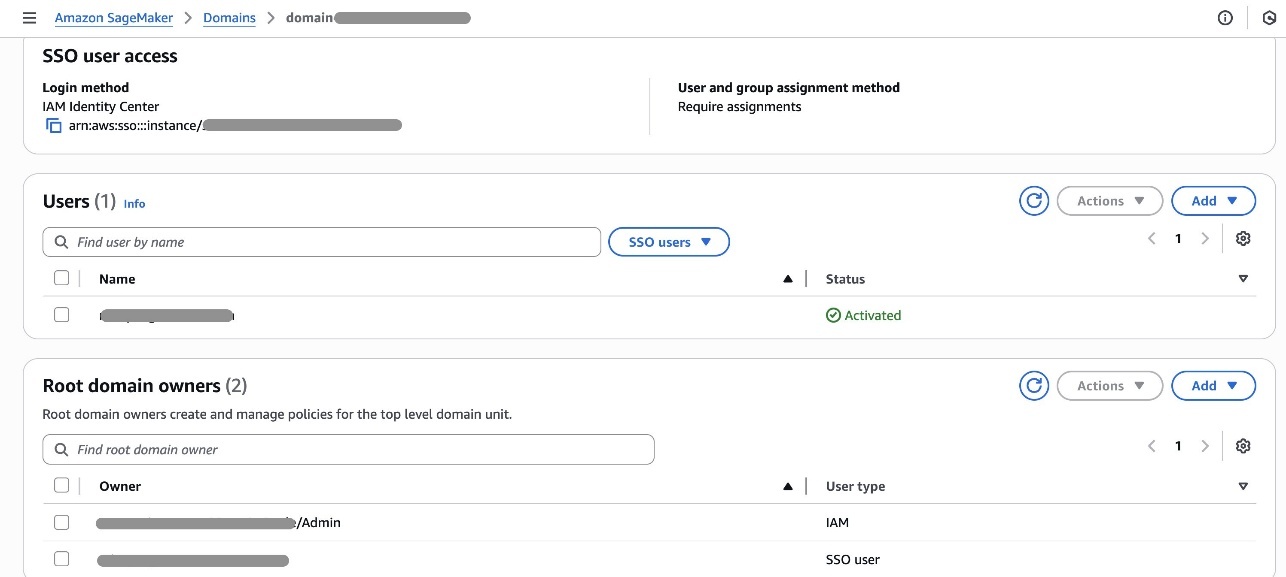
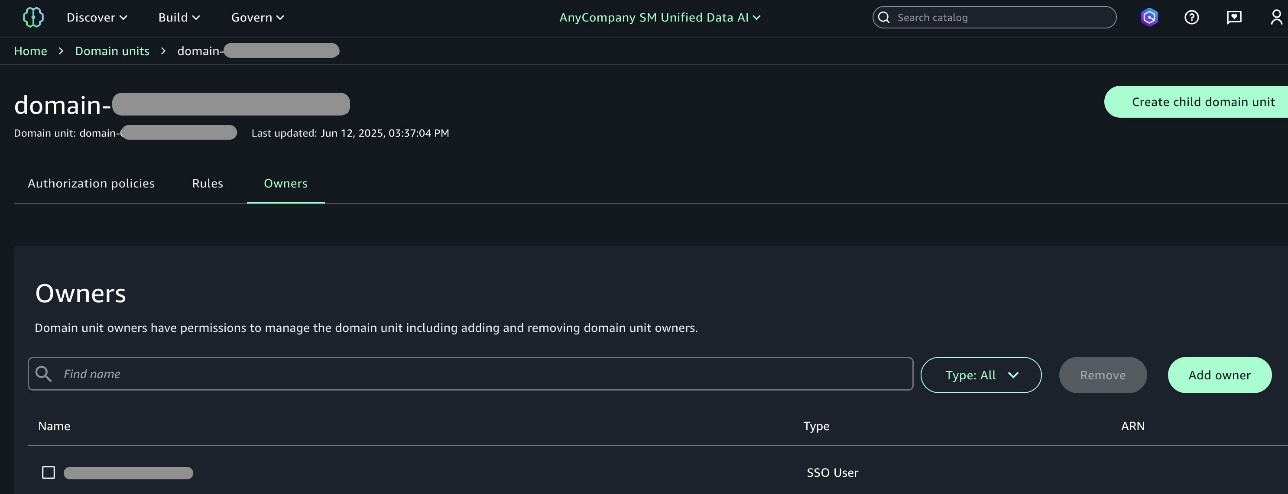
Now that as an admin you have created the environments for different business units, your next step is to add domain owner users to the respective domain units. First, you must add domain and project owners’ users for them to get access to the SageMaker Unified Studio domain portal.

ATPCO-Solution-SMUS-Domain-6

Domain units make it possible to organize your assets and other domain entities under specific business units and teams. Domain unit owners can create policies such as membership, domain, and project creation.

ATPCO-Solution-SMUS-Owner-7

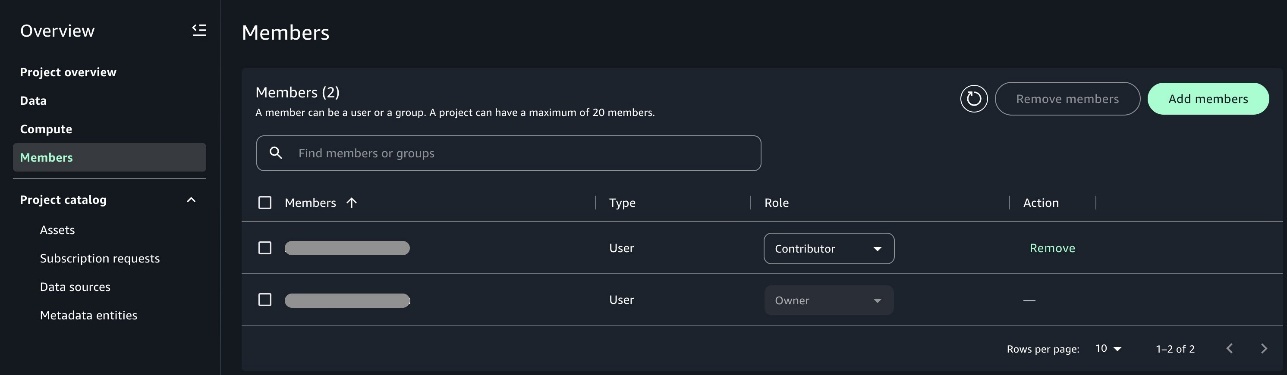
Domain unit owners can add one of the members as owner of the project so that when the owner user logs in, they can add other users of their team as an owner or contributor to the project. This helps other users get access to the projects when they login to SageMaker Unified Studio.

ATPCO-Solution-SMUS-members-8

Use the SageMaker Unified Studio environment

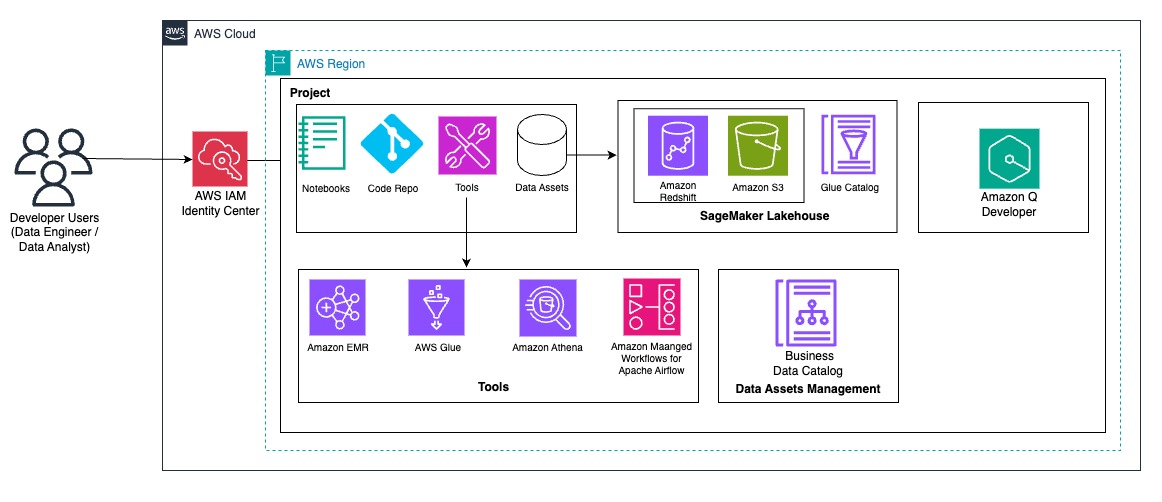
After the admin completes the required setup for different business units and onboardsproject members, users can log in to the portal and start using the preconfigured SageMaker Unified Studio environment. Users have access to respective data sources and tools as shown in the following developer flow diagram.

ATPCO-Solution-SMUS-DeveloperFlow-9

At ATPCO, developers must often combine data from various sources to perform extract, transform, and load (ETL) processes efficiently. In this section, we demonstrate how developers can benefit from the SageMaker unified lakehouse environment by seamlessly integrating data from both Amazon Redshift and the Data Catalog. Using PySpark within SageMaker Unified Studio notebooks, we read transactional data from Amazon Redshift and enrich it with metadata stored in AWS Glue backed S3 tables such as warehouse or product attributes. This integrated view supports complex transformations and aggregations across disparate sources without needing to move or duplicate data. By using native connectors and Spark’s distributed processing, users can join, filter, and analyze multi-source datasets efficiently and write the results back to Amazon Redshift for downstream analytics or dashboarding, all within a single, interactive lakehouse interface.

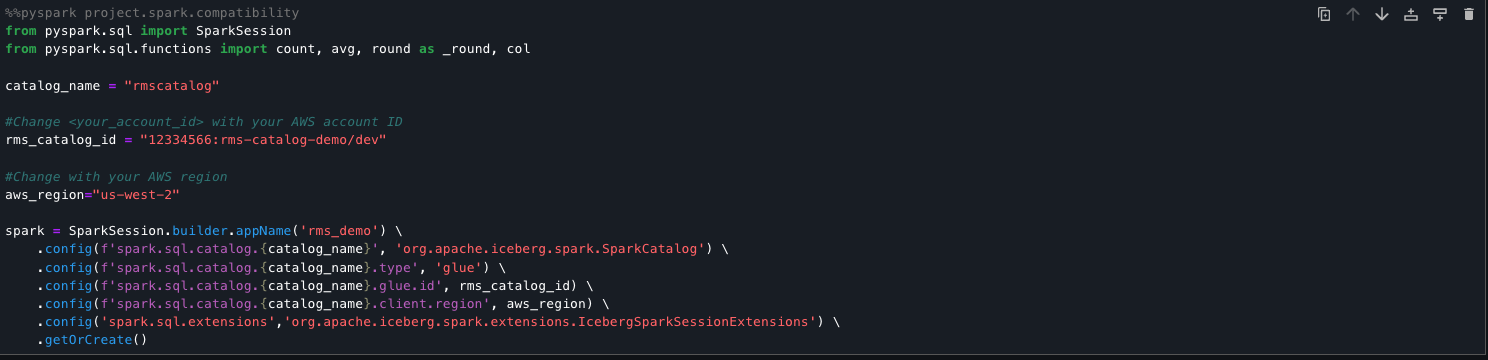
The following code snippet sets up a Spark session to directly query Amazon Redshift managed storage tables using the lakehouse architecture. It registers an AWS Glue backed Iceberg catalog (rmscatalog) that points to a specific Redshift lakehouse catalog and database, allowing Spark to read from and write to Redshift Iceberg tables. By enabling Iceberg extensions and linking the catalog to AWS Glue and Lake Formation, this setup provides seamless, scalable access to Amazon Redshift managed data using standard Spark SQL.

from pyspark.sql import SparkSession
from pyspark.sql.functions import count, avg, round as _round, col
catalog_name = "rmscatalog"
#Change <your_account_id> with your AWS account ID
rms_catalog_id = "<your_account_id>:rms-catalog-demo/dev"
#Change with your AWS region
aws_region="<region>"
spark = SparkSession.builder.appName('rms_demo') \
.config(f'spark.sql.catalog.{catalog_name}', 'org.apache.iceberg.spark.SparkCatalog') \
.config(f'spark.sql.catalog.{catalog_name}.type', 'glue') \
.config(f'spark.sql.catalog.{catalog_name}.glue.id', rms_catalog_id) \
.config(f'spark.sql.catalog.{catalog_name}.client.region', aws_region) \
.config('spark.sql.extensions','org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions').getOrCreate()

ATPCO-Solution-SMUS-Code-10

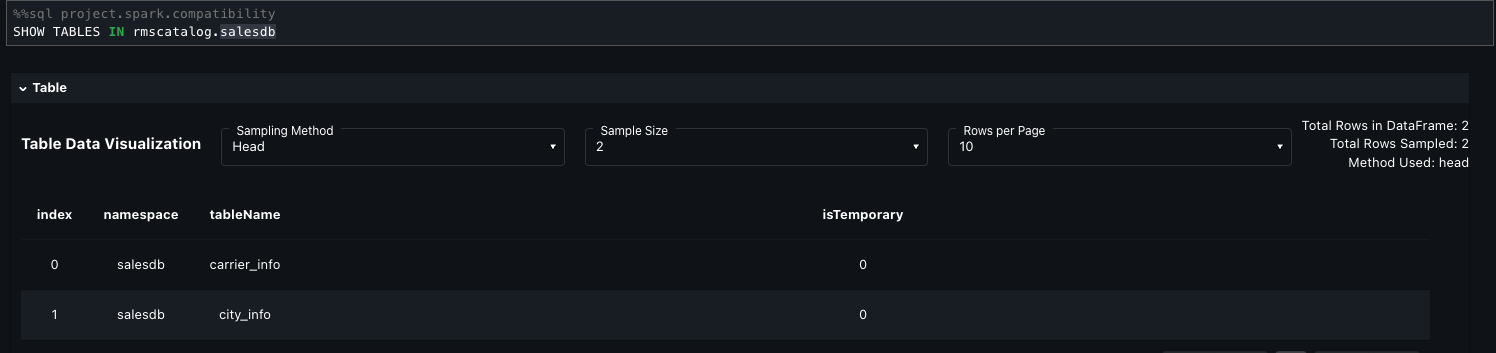
=== Check for the tables and load them into dataframes
SHOW TABLES IN rmscatalog.salesdb

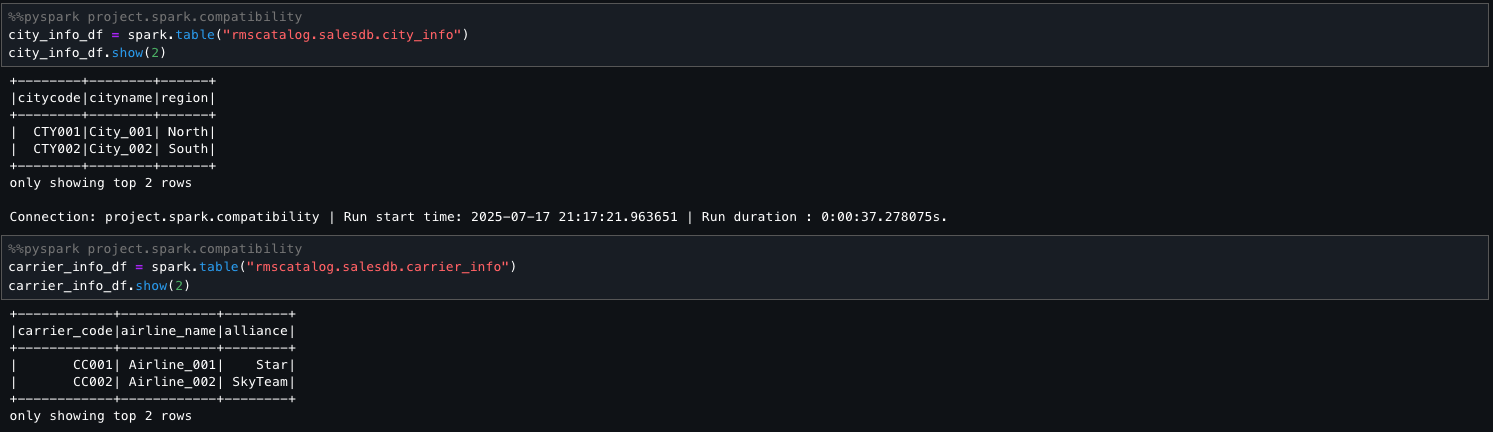
ATPCO-Solution-SMUS-Code-11

city_info_df = spark.table("rmscatalog.salesdb.city_info") 
carrier_info_df = spark.table("rmscatalog.salesdb.carrier_info")

ATPCO-Solution-SMUS-Code-12

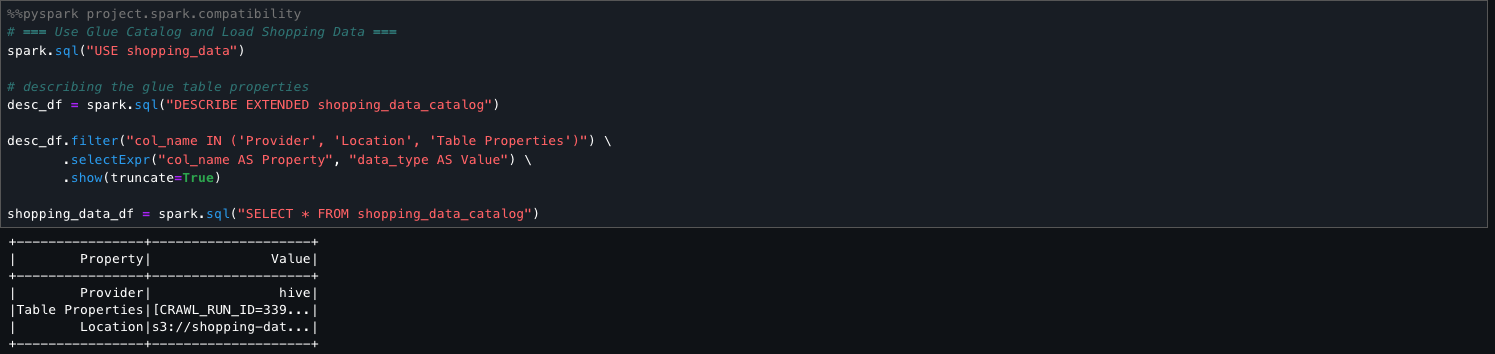
The following step sets the active AWS Glue database to shopping_data and retrieves metadata for the shopping_data_catalog table using DESCRIBE EXTENDED. It filters for key properties like Provider, Location, and Table Properties to understand the table’s storage and configuration. Finally, it loads the entire table into a Spark DataFrame (shopping_data_df) for downstream processing.

# === Use Glue Catalog and Load Shopping Data ===
spark.sql("USE shopping_data")
# describing the glue table properties
desc_df = spark.sql("DESCRIBE EXTENDED shopping_data_catalog")
desc_df.filter("col_name IN ('Provider', 'Location', 'Table Properties')") \
.selectExpr("col_name AS Property", "data_type AS Value") \
.show(truncate=True)
shopping_data_df = spark.sql("SELECT * FROM shopping_data_catalog")

ATPCO-Solution-SMUS-Code-13

The following code shows how you can seamlessly combine and aggregate two disparate data sources, Amazon Redshift and the Data Catalog, within SageMaker Unified Studio. Using PySpark, we perform transformations and derive meaningful summaries across the unified view. This facilitates streamlined analysis and reporting without the need for complex data movement or duplication.

# == Join and Aggregate Data ===
shopping_with_cities_df = shopping_data_df \
.join(city_info_df.alias("origin_city"), shopping_data_df.origincitycode == col("origin_city.citycode"), "left") \
.join(city_info_df.alias("dest_city"), shopping_data_df.destinationcitycode == col("dest_city.citycode"), "left")
shopping_full_df = shopping_with_cities_df \
.join(carrier_info_df, col("validatingcarrier") == col("carrier_code"), "left")
result_df = shopping_full_df.groupBy("origin_city.region", "alliance") \
.agg(
count("*").alias("total_trips"),
_round(avg("totalamount"), 2).alias("avg_amount")
) \
.orderBy("total_trips", ascending=False)
result_df.show(10, truncate=False)

ATPCO-Solution-SMUS-Code-14

After the job runs, it writes the transformed dataset directly into a Data Catalog table that is Iceberg-compatible. This integration makes sure the data is stored in Amazon S3 with ACID transaction support, and also registered and tracked in the Data Catalog for unified governance, schema discovery, and downstream query access. The Iceberg table format organizes the data into Parquet files under a data/ directory and maintains rich versioned metadata in a metadata/ folder, supporting features like schema evolution, time travel, and partition pruning. This design facilitates scalable, reliable, and SQL-compatible analytics on modern data lakes.

ATPCO-Solution-SMUS-Code-15

ATPCO-Solution-SMUS-Data-File-16

The table becomes immediately available for querying through the Athena query editor, providing interactive access to fresh, transactional data without additional ingestion steps or manual registration.This approach streamlines the end-to-end data flow, from processing in Spark to interactive querying in Athena within the modern SageMaker Lakehouse environment.

ATPCO-Solution-SMUS-Query-Data-16

Conclusion

This post walked you through the steps to prepare a SageMaker Unified Studio environment for a company-wide rollout, using APTCO’s journey as an example. We covered the domain design and admin flow, which is a one-time setup to prepare the SageMaker Unified Studio environment for different teams in the organization who requires different levels of access to the data and tools. After the admin flow, we demonstrated the developer flow and how to use tools like a Jupyter notebook and SQL editor to use the data across different sources such as Amazon S3, the Data Catalog, and Redshift assets to perform a unified analysis.

Try out this solution and get started with SageMaker Unified Studio and modernize with the next generation of SageMaker. To learn more about SageMaker Unified Studio and how to get started, refer to the Amazon SageMaker Unified Studio Administrator Guide, and the latest AWS Big Data Blog posts.


About the authors

Mitesh Patel is a Principal Solutions Architect at AWS. His passion is helping customers harness the power of Analytics, Machine Learning, AI & GenAI to drive business growth. He engages with customers to create innovative solutions on AWS.

Nikki Rouda works in product marketing at AWS. He has many years experience across a wide range of IT infrastructure, storage, networking, security, IoT, analytics, and modern applications.

Raj Samineni is the Director of Data Engineering at ATPCO, leading the creation of advanced cloud-based data platforms. His work ensures robust, scalable solutions that support the airline industry’s strategic transformational objectives. By leveraging machine learning and AI, Raj drives innovation and data culture, positioning ATPCO at the forefront of technological advancement.

Saurabh Rawat is a Solution Architect at AWS with 13 years of experience working with enterprise data systems. He has designed and delivered large-scale, cloud-native solutions for customers across industries, with a focus on data engineering, analytics, and well-architected architectures. Over his career, he has helped organizations modernize their data platforms, optimize for performance, and cost, and adopt best practices for scalability and security. Outside of work, he is a passionate musician and enjoys playing with his band.

OpenAI open weight models now available on AWS

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/openai-open-weight-models-now-available-on-aws/

AWS is committed to bringing you the most advanced foundation models (FMs) in the industry, continuously expanding our selection to include groundbreaking models from leading AI innovators so that you always have access to the latest advancements to drive your business forward.

Today, I am happy to announce the availability of two new OpenAI models with open weights in Amazon Bedrock and Amazon SageMaker JumpStart. OpenAI gpt-oss-120b and gpt-oss-20b models are designed for text generation and reasoning tasks, offering developers and organizations new options to build AI applications with complete control over their infrastructure and data.

These open weight models excel at coding, scientific analysis, and mathematical reasoning, with performance comparable to leading alternatives. Both models support a 128K context window and provide adjustable reasoning levels (low/medium/high) to match your specific use case requirements. The models support external tools to enhance their capabilities and can be used in an agentic workflow, for example, using a framework like Strands Agents.

With Amazon Bedrock and Amazon SageMaker JumpStart, AWS gives you the freedom to innovate with access to hundreds of FMs from leading AI companies, including OpenAI open weight models. With our comprehensive selection of models, you can match your AI workloads to the perfect model every time.

Through Amazon Bedrock, you can seamlessly experiment with different models, mix and match capabilities, and switch between providers without rewriting code—turning model choice into a strategic advantage that helps you continuously evolve your AI strategy as new innovations emerge. At launch, these new models are available in Bedrock via an OpenAI compatible endpoint. You can point the OpenAI SDK to this endpoint or use the Bedrock InvokeModel and Converse API.

With SageMaker JumpStart, you can quickly evaluate, compare, and customize models for your use case. You can then deploy the original or the customized model in production with the SageMaker AI console or using the SageMaker Python SDK.

Let’s see how these work in practice.

Getting started with OpenAI open weight models in Amazon Bedrock
In the Amazon Bedrock console, I choose Model access from the Configure and learn section of the navigation pane. Then, I navigate to the two listed OpenAI models on this page and request access.

Console screenshot

Now that I have access, I use the Chat/Test playground to test and evaluate the models. I select OpenAI as the category and then the gpt-oss-120b model.

Console screenshot

Using this model, I run the following sample prompt:

A family has $5,000 to save for their vacation next year. They can place the money in a savings account earning 2% interest annually or in a certificate of deposit earning 4% interest annually but with no access to the funds until the vacation. If they need $1,000 for emergency expenses during the year, how should they divide their money between the two options to maximize their vacation fund?

This prompt generates an output that includes the chain of thought used to produce the result.

I can use these models with the OpenAI SDK by configuring the API endpoint (base URL) and using an Amazon Bedrock API key for authentication. For example, I set this environment variables to use the US West (Oregon) AWS Region endpoint (us-west-2) and my Amazon Bedrock API key:

export OPENAI_API_KEY="<my-bedrock-api-key>"
export OPENAI_BASE_URL="https://bedrock-runtime.us-west-2.amazonaws.com/openai/v1"

Now I invoke the model using the OpenAI Python SDK.

client = OpenAI()

response = client.chat.completion.create(
    messages=[{
        "role": "user",
        "content": "Hello, how are you?"
    }],
    model="openai.gpt-oss-120b-1:0",
    stream=True
)

for item in response:
    print(item)

To build an AI agent, I can choose any framework that supports the Amazon Bedrock API or the OpenAI API. For example, here’s the starting code for Strands Agents using the Amazon Bedrock API:

from strands import Agent
from strands.models import BedrockModel
from strands_tools import calculator

model = BedrockModel(
    model_id="openai.gpt-oss-120b-1:0"
)
agent = Agent(
    model=model,
    tools=[calculator]
)

agent("Tell me the square root of 42 ^ 3")

I save the code (app.py file), install the dependencies, and run the agent locally:

pip install strands-agents strands-agents-tools
python app.py

When I am satisfied with the agent, I can deploy in production using the capabilities offered by Amazon Bedrock AgentCore, including a fully managed serverless runtime and memory and identity management.

Getting started with OpenAI open weight models in Amazon SageMaker JumpStart
In the Amazon SageMaker AI console, you can use OpenAI open weight models in the SageMaker Studio. The first time I do this, I need to set up a SageMaker domain. There are options to set it up for a single user (simpler) or an organization. For these tests, I use a single user setup.

In the SageMaker JumpStart model view, I have access to a detailed description of the gpt-oss-120b or gpt-oss-20b model.

I choose the gpt-oss-20b model and then deploy the model. In the next steps, I select the instance type and the initial instance count. After a few minutes, the deployment creates an endpoint that I can then invoke in SageMaker Studio and using any AWS SDKs.

To learn more, visit GPT OSS models from OpenAI are now available on SageMaker JumpStart in the AWS Artificial Intelligence Blog.

Things to know
The new OpenAI open weight models are now available in Amazon Bedrock in the US West (Oregon) AWS Region, while Amazon SageMaker JumpStart supports these models in US East (Ohio, N. Virginia) and Asia Pacific (Mumbai, Tokyo).

Each model comes equipped with full chain-of-thought output capabilities, providing you with detailed visibility into the model’s reasoning process. This transparency is particularly valuable for applications requiring high levels of interpretability and validation. These models give you the freedom to modify, adapt, and customize them to your specific needs. This flexibility allows you to fine-tune the models for your unique use cases, integrate them into your existing workflows, and even build upon them to create new, specialized models tailored to your industry or application.

Security and safety are built into the core of these models, with comprehensive evaluation processes and safety measures in place. The models maintain compatibility with the standard GPT-4 tokenizer.

Both models can be used in your preferred environment, whether that’s through the serverless experience of Amazon Bedrock or the extensive machine learning (ML) development capabilities of SageMaker JumpStart. For information about the costs associated with using these models and services, visit the Amazon Bedrock pricing and Amazon SageMaker AI pricing pages.

To learn more, see the parameters for the models and the chat completions API in the Amazon Bedrock documentation.

Get started today with OpenAI open weight models on AWS in the Amazon Bedrock console or in Amazon SageMaker AI console.

Danilo

Integrate scientific data management and analytics with the next generation of Amazon SageMaker, Part 1

Post Syndicated from Nadeem Bulsara original https://aws.amazon.com/blogs/big-data/integrate-scientific-data-management-and-analytics-with-the-next-generation-of-amazon-sagemaker-part-1/

Our customers tell us that scientists are increasingly spending more time managing data-related challenges than focusing on science. The primary reason for this challenge is that scientific data comes in many types and is siloed across systems, groups, and stages, and scientists struggle to efficiently discover, access, share, and analyze datasets across silos. This fragmentation creates lengthy cycles full of manual interventions, leading to inefficiencies. Mapping data sources and negotiating access across silos can take 4–6 weeks, integrating datasets can extend to months, and fully connecting data from source to tooling can take years, if ever achieved. These data challenges reduce lab productivity and slow down scientific innovation, which decrease drug and product pipeline throughput, and ultimately delay time-to-market. The solution lies in breaking down data silos by creating digital environments that help scientists efficiently connect disparate datasets and analytical tools, so they can conduct iterative hypothesis and product testing without technology friction.

Part 1 of this series shows an example project in drug target identification where two groups of scientists need to collaborate as they integrate no-code knowledge searching, scientific data management, and sophisticated analytics. In this example, a computational biology team begins by mining the scientific literature on a knowledge search GUI. Next, they navigate to a data catalog to find and access relevant datasets, which they share with the data scientist team to run analytics with sophisticated tools (see the following figure). Although the end-to-end journey illustrates the benefits to a target identification example, the underlying data challenges and technology solution apply to any life sciences use case requiring the integration of data management and analytics. Details of the implementation and technical solution will be discussed in Part 2 of the series.

A flow diagram with a dark background starting with Scientific data. It shows people with stock images as example personas that use the data to derive insights.

Example use case

A computational biologist has been tasked with identifying a target for Non-Alcoholic Fatty Liver Disease (NAFLD). A typical question from the biologist might be “Can I find genes associated with NAFLD and do we have a patient cohort with variants in those genes?” The solution we designed for this use case involves three simple steps:

  1. Search the scientific literature through a no-code interface to identify genomic variants associated with NAFLD.
  2. Search an internal data catalog with natural language:
    • Find datasets of interest, such as multi-omics and clinical data for patients associated with NAFLD.
    • Request access to the relevant datasets.
  3. Share relevant datasets with a data scientist collaborator for deeper analysis.

In designing this solution, we focused on the following features:

  • Providing no-code scientists with point-and-click and natural-language interfaces
  • Reducing silos with data findability, governance automation, and seamless collaboration
  • Providing technical personas with the sophisticated tools and environments they prefer

Solution overview

This solution uses the next generation of Amazon SageMaker, including Amazon SageMaker Unified Studio, an integrated data and AI development environment. SageMaker Unified Studio offers capabilities for data processing, SQL analytics, model development, and generative AI application development, built on existing AWS services. The next generation of SageMaker also includes Amazon SageMaker Catalog, which is built on Amazon DataZone, a data management service designed to streamline data discovery, data cataloging, data sharing, and governance. Your organization can have a single secure data hub where everyone in the organization can find, access, and collaborate on data across AWS, on premises, and even third-party sources.

SageMaker Catalog supports certain system asset types, such as tables from Amazon Redshift, tables from AWS Glue, and object collections from Amazon Simple Storage Service (Amazon S3). It also offers the ability to support custom asset types, which gives users flexibility to catalog data that can’t be categorized as a system asset type. For asset type S3ObjectCollectionType, see Implement a custom subscription workflow for unmanaged Amazon S3 assets published with Amazon DataZone. SageMaker Catalog also offers the ability to support custom asset types, which gives users flexibility to catalog data that can’t be categorized as a system asset type. For this example use case, we used AWS HealthOmics variant stores to store and allow querying of genomic variant data. This example lists HealthOmics variant stores as a custom asset type within the catalog. Details of the implementation and technical solution for access management will be discussed in Part 2 of the series.

In the example use case, a computational biologist, in order to identify a target for NAFLD, relies heavily on diverse datasets from multiple sources (genomic sequences, gene expression data, clinical records, and more). This data comes from both internal sources (first-party) and external partners or public databases (third-party). Multiple teams are responsible for collecting and processing this data before making it available to computational biologists, researchers, data scientists, and bioinformaticians within the organization.

In this solution, users (data engineers, data scientists, bioinformaticians, computational biologists) log in to a project-based environment from SageMaker Unified Studio with a preconfigured authentication method. A typical workflow involves the following steps:

  1. Data stewards as authorized members of projects publish data assets into the SageMaker catalog.
  2. Data consumers as authorized members of projects seeking to analyze data for their scientific needs find and discover available data assets of interest from the SageMaker catalog.
  3. Data consumers request to subscribe to the relevant discovered data assets.
  4. Data producers review and decide to approve or reject the subscription request.
  5. Data consumers access and analyze the data using preconfigured tools from SageMaker Unified Studio.

The following diagram illustrates the solution architecture and workflow.

architecture diagram

In the following sections, we explore each step of the workflow in more detail.

Step 1: Data producers publish data assets

As shown in the preceding workflow diagram, data producers can use SageMaker Catalog to publish their datasets as data assets or data products with appropriate business (such as source, license, vendor, study identifier), scientific (such as disease name, cohort information, data modality, assay type), or technical (file types, data formats, file sizes) metadata. In our example use case, the data producers publish clinical data as AWS Glue tables and genomic variant data as a table within the HealthOmics variant store. Additionally, data producers can use AI-based recommendations to automatically populate descriptors, making it straightforward for consumers to find and understand its use.

Step 2: Data consumers find relevant datasets

Data consumers, such as data scientists and bioinformaticians, can log in to SageMaker Unified Studio and navigate to SageMaker Catalog to search for the appropriate data assets and products, such as “NAFLD Variants” or “NAFLD Clinical.” They can also find data assets or products using metadata filters such as study identifiers or disease names to discover the possible datasets associated with a study or disease.

Step 3: Data consumers subscribe to required data assets or products

After the data consumers see a data asset or data product of interest (for example, the clinical and genomics data for NAFLD), they can subscribe to them. Data consumers can also optionally include a comment in the subscription request to add more context to the request. This initiates the subscription workflow based on the asset type.

Step 4: Data producers review and approve the subscription request

Data producers get notified of subscription requests and review if access should be granted and approve accordingly. The response can optionally include a comment for reasoning and traceability. In addition, data producers can limit access to certain rows and columns to protect controlled data.

Step 5: Data consumers access the subscribed data assets or products

Upon approval from the data producer, the data consumer gets access to those data assets and can use them in the appropriate environments configured within their project. For example, data scientists can open a workspace with a JupyterLab notebook already available within SageMaker Unified Studio. Subsequently, the data scientist can start analyzing the tabular clinical and variant data that was just approved for access.

Conclusion

The next generation of SageMaker transforms how scientists work with data by creating an integrated data and analytics environment. In this unified environment, data producers are empowered to publish datasets with rich metadata. Data consumers are able to use the catalog within SageMaker Unified Studio to search for their required datasets, either using free text or using metadata and business glossary filters. Data consumers can subscribe to data securely, tap into powerful search capabilities using free text or metadata filters, and access essential analysis tools (Amazon Athena, JupyterLab IDE, Amazon EMR) directly. The result is a unified digital workspace that reduces communication bottlenecks, speeds up scientific cycles, and removes technical barriers. Scientists can now focus on what matters most—testing hypotheses and products, and scaling scientific innovation to production—within a unified, powerful platform. This streamlined approach accelerates data-driven science, enabling research institutions, pharmaceutical companies, and clinical laboratories to innovate more efficiently. For example, data scientists can launch a space with a JupyterLab notebook preinstalled.

Consider using the next generation of SageMaker to increase productivity within your organization. Contact your account representatives or an AWS Representative to learn how we can help accelerate your projects and your business.


About the authors

Nadeem Bulsara is a Principal Solutions Architect at AWS specializing in Genomics and Life Sciences. He brings his 13+ years of Bioinformatics, Software Engineering, and Cloud Development skills as well as experience in research and clinical genomics and multi-omics to help Healthcare and Life Sciences organizations globally. He is motivated by the industry’s mission to enable people to have a long and healthy life.

Chaitanya Vejendla is a Senior Solutions Architect specialized in DataLake & Analytics primarily working for Healthcare and Life Sciences industry division at AWS. Chaitanya is responsible for helping life sciences organizations and healthcare companies in developing modern data strategies, deploy data governance and analytical applications, electronic medical records, devices, and AI/ML-based applications, while educating customers about how to build secure, scalable, and cost-effective AWS solutions. His expertise spans across data analytics, data governance, AI, ML, big data, and healthcare-related technologies.

Dr. Mileidy Giraldo has over 20 years of experience bridging bioinformatics, research, and industry technology strategy. She specializes in making technology accessible for organizations in the life sciences sector. In her current role as WW Lead for Life Sciences Strategy and Lab of the Future at AWS, she helps biotechs, biopharma, and diagnostics organizations design Data & AI-driven initiatives that modernize labs and help scientists unlock the full value of their data.

Chris Clark is a Senior Solutions Architect focused on helping Life Science customers leverage AWS technology to advance their operational capabilities. With 20+ years of hands-on experience in life sciences manufacturing and supply chain, he combines deep industry knowledge with his AWS expertise to guide his customers. When he’s not working to solve customer challenges, he enjoys cycling and building and repairing things in his workshop.

Nick Furr is a Specialist Solutions Architect at AWS, supporting Data & Analytics for Healthcare and Life Sciences. He helps providers, payers, and life sciences organizations build secure, scalable data platforms to drive innovation and improve outcomes. His work focuses on modernizing data strategies through cloud analytics, governed data processing, and machine learning for use cases like clinical research and population health.

Subrat Das is a Principal Solutions Architect for Global Healthcare and Life Sciences accounts at AWS. He is passionate about modernizing and architecting complex customers workloads. When he’s not working on technology solutions, he enjoys long hikes and traveling around the world.

Develop and deploy a generative AI application using Amazon SageMaker Unified Studio

Post Syndicated from Amit Maindola original https://aws.amazon.com/blogs/big-data/develop-and-deploy-a-generative-ai-application-using-amazon-sagemaker-unified-studio/

Picture this: You’re a financial analyst starting your Monday morning with a steaming cup of coffee, ready to review your investment portfolio. But instead of manually scouring dozens of news websites, financial reports, and industry analyses, you simply ask your AI assistant: “What global events happened over the weekend that might impact my technology stock holdings?” Within seconds, you receive a comprehensive analysis of relevant news, sentiment scores, and potential investment implications—all powered by a sophisticated generative AI application you built yourself.

This scenario isn’t science fiction; it’s the reality that modern financial professionals can create today. In an era where information moves at the speed of light and industry conditions can shift dramatically overnight, staying informed isn’t just an advantage—it’s essential for survival in competitive financial landscapes. The challenge lies in processing the overwhelming volume of global information that could impact investments while distinguishing reliable insights from noise.

Amazon SageMaker – Develop and scale AI use cases with the broadest set of tools

Luckily for us, technology is making this more straightforward. The next generation of Amazon SageMaker with Amazon SageMaker Unified Studio is a single data and AI development environment where you can find and access the data in your organization and act on it using the best tools across different use cases. SageMaker Unified Studio brings together the functionality and tools from existing AWS analytics and artificial intelligence and machine learning (AI/ML) services, including Amazon EMR , AWS Glue, Amazon Athena, Amazon Redshift , Amazon Bedrock, and Amazon SageMaker AI. From within SageMaker Unified Studio, you can find, access, and query data and AI assets across your organization, then work together in projects to securely build and share analytics and AI artifacts, including data, models, and generative AI applications.

With SageMaker Unified Studio, you can efficiently build generative AI applications in a trusted and secure environment using Amazon Bedrock. You can choose from a selection of high-performing foundation models (FMs) and advanced customization capabilities like Amazon Bedrock Knowledge Bases, Amazon Bedrock Guardrails, Amazon Bedrock Agents, and Amazon Bedrock Flows. You can rapidly tailor and deploy generative AI applications and share with the built-in catalog for discovery.

What makes SageMaker Unified Studio particularly powerful for organizations is its integration with Amazon Bedrock Flows to build generative AI workflows, which is changing how organizations think about AI application development.

Amazon Bedrock Flows for generative AI application development

With Amazon Bedrock Flows, you can build and execute complex generative AI workflows without writing code, using an intuitive visual interface that democratizes AI development. This capability is transformative for organizations where speed, accuracy, and adaptability are paramount. It offers the following benefits:

  • Visual workflow development – Users can design AI applications by dragging and dropping components onto a canvas, making AI logic transparent and modifiable
  • Business logic flexibility – The service supports complex business logic through conditional branching, multi-path decision trees, and dynamic routing
  • Democratizing AI development – Business experts can directly contribute to AI application development without requiring extensive technical expertise
  • Seamless integration – Amazon Bedrock Flows integrates with FMs, knowledge bases, guardrails, and other AWS services
  • Reduced development complexity – The service handles infrastructure management and scaling through serverless execution and SDK APIs

Solution overview

In this post, we explore a financial use case, in which we want to stay on top of latest global events and determine our investment or financial exposure based on this. We can use a SageMaker Unified Studio flow application to pull in latest news summaries, derive sentiment based on news summary, and determine their effects on my investments. The following diagram illustrates this use case.

In the following sections, we show how to create a new project and build a flow application using a generative AI profile in SageMaker Unified Studio.

Prerequisites

For this walkthrough, you must have the following prerequisites:

  • A demo project – Create a demo project in your SageMaker Unified Studio domain. For instructions, see Create a project. For this example, we choose All capabilities in the project profile section, which includes the generative AI project profile enabled.

Create new project and build a flow application in SageMaker Unified Studio

In this section, we create a new a flow application that uses an Amazon Bedrock knowledge base to provide information about your personal portfolio. Complete the following steps:

  1. In SageMaker Unified Studio, open the project you created as a prerequisite and choose Build and then Flow.

  1. Drag Knowledge Base from Nodes to the design panel to add a knowledge base that will include the user’s investment portfolio and news articles and other information like earnings call transcripts, financial analyst reports, and so on.

  1. Choose the Knowledge Base node and configure the knowledge base as follows:
  2. Add a name for your knowledge base name (for example, portfolio…).
  3. Choose the model (for example, Claude 3.5 Haiku).

  1. Choose Create new Knowledge Base.
  2. Enter a name for the knowledge base.
  3. Select Project data source.
  4. For Select a data source, choose the Amazon Simple Storage Service (Amazon S3) bucket location where you uploaded your data.
  5. Choose Create.

The knowledge base creation process takes a few minutes to complete.

  1. When the knowledge base is ready, choose Save to save it to the flow.

  1. Choose My components, and on the options menu (three vertical dots), choose Sync to sync the knowledge base.

Make sure the S3 bucket has all the data (user portfolio data and latest news information data) before syncing the knowledge base.

We don’t provide any financial or news information data as part of this post. Upload current events or news data and investment portfolio data from your own data sources.

Test the flow application

After the knowledge base sync is complete, you can return to the flow application and ask questions. Using SageMaker Unified Studio flows, a financial analyst can provide a more personalized and customized financial outlook to their customers using rich internal financial information on their customer’s investment portfolio and latest publicly available current events and news information. The following are some example questions that you can ask to test the knowledge base:

Check if Tesla or Apple is in any of user's investment portfolio

Please check latest news information to provide information if Tesla has positive, negative or neutral outlook in the near future

Flow-based applications offer a visual approach to creating complex AI workflows. By chaining different nodes, each optimized for specific functions, you can create sophisticated solutions that are more reliable, maintainable, and efficient than single-prompt approaches. These flows allow for conditional logic and branching paths, mimicking human decision-making processes and enabling more nuanced responses based on context and intermediate results.

Clean up

To avoid ongoing charges in your AWS account, delete the resources you created during this tutorial:

  1. Delete the project.
  2. Delete the domain created as part of the prerequisites.

Conclusion

In this post, we demonstrated how to use Amazon Bedrock Flows in SageMaker Unified Studio to build a sophisticated generative AI application for financial analysis and investment decision-making without extensive coding knowledge. With this integration, you can create sophisticated financial analysis workflows through an intuitive visual interface, where you can process industry data, analyze news sentiment, and assess investment implications in real time. The solution integrates seamlessly with AWS services and FMs while providing essential features like automatic scaling, compliance controls, and audit capabilities. The implementation process involves setting up a SageMaker Unified Studio domain, configuring knowledge bases with portfolio and news data, and creating visual workflows that can analyze complex financial information. This democratized approach to AI development allows both technical and business teams to collaborate effectively, significantly reducing development time while maintaining the sophisticated capabilities needed for modern financial analysis.

To get started, explore the SageMaker Unified Studio documentation, set up a project in your AWS environment, and discover how this solution can transform your organization’s data analytics capabilities.


About the authors

Amit Maindola is a Senior Data Architect focused on data engineering, analytics, and AI/ML at Amazon Web Services. He helps customers in their digital transformation journey and enables them to build highly scalable, robust, and secure cloud-based analytical solutions on AWS to gain timely insights and make critical business decisions.

Arghya Banerjee is a Sr. Solutions Architect at AWS in the San Francisco Bay Area, focused on helping customers adopt and use the AWS Cloud. He is focused on big data, data lakes, streaming and batch analytics services, and generative AI technologies.

Melody Yang is a Principal Analytics Architect for Amazon EMR at AWS. She is an experienced analytics leader working with AWS customers to provide best practice guidance and technical advice in order to assist their success in data transformation. Her areas of interests are open-source frameworks and automation, data engineering and DataOps.

Gaurav Parekh is a Solutions Architect at AWS, specializing in generative AI and data analytics, with extensive experience building production AI systems on AWS.

Automate data lineage in Amazon SageMaker using AWS Glue Crawlers supported data sources

Post Syndicated from Mohit Dawar original https://aws.amazon.com/blogs/big-data/automate-data-lineage-in-amazon-sagemaker-using-aws-glue-crawlers-supported-data-sources/

The next generation of Amazon SageMaker is the center for all your data, analytics, and AI. Bringing together widely adopted Amazon Web Services (AWS) machine learning (ML) and analytics capabilities, it delivers an integrated experience for analytics and AI with unified access to all your data. From Amazon SageMaker Unified Studio, a single data and AI development environment, you can access your data and use a suite of powerful tools for data processing, SQL analytics, model development, training and inference, and generative AI development.

With data lineage, now part of Amazon SageMaker Catalog, you can centralize lineage metadata of your data assets in a single place. You can track the flow of data over time, determining a clear understanding of where it originated, how it has changed, and its usage across the business. By providing this level of transparency, data lineage helps data consumers gain trust that the data is correct and compliant for their use cases. With data lineage captured at the table, column, and job level, data producers can conduct impact analysis of changes in their data pipelines and respond to data issues when needed, for example, when a column in the resulting dataset is missing the quality required by the business.

Data lineage is a powerful tool that can transform how organizations understand and manage their data flows. In this post, we explore its real-world impact through the lens of an ecommerce company striving to boost their bottom line.

To illustrate this practical application, we walk you through how you can use the prebuilt integration between SageMaker Catalog and AWS Glue crawlers to automatically capture lineage for data assets stored in Amazon Simple Storage Service (Amazon S3) and Amazon DynamoDB. Using this workflow, you can capture lineage automatically from additional data sources using AWS Glue crawlers. Refer to the Data lineage support matrix in the SageMaker Unified Studio User Guide for supported sources. We also use SageMaker Unified Studio to navigate these data assets and learn about their origin, transformations, and dependencies, thanks to the lineage metadata captured using the AWS Glue crawlers.

Key features of the SageMaker Catalog lineage graph

In SageMaker Unified Studio, you can explore and discover data assets of your organization suited for your use case. As you dive into these data assets, you can learn more about its business context, schema, quality, and lineage. When you decide to work with a subset of these assets, you can subscribe to them in a self-service fashion and start working with them. For more detail, visit Data discovery, subscription, and consumption in the SageMaker Unified Studio User Guide.

SageMaker Studio provides a visual lineage graph that shows how a data asset has evolved from its source through transformations to its final state. This helps data scientists, engineers, and analysts answer key questions such as:

  • Where did this data come from?
  • What transformations has it gone through?
  • Which downstream assets will be impacted by a change?

With this level of visibility, teams can perform faster impact analysis, find the root cause of data quality issues, and ensure models are built on trusted data. It also supports better collaboration so users can confidently use and share data across the organization. The following screenshot shows how SageMaker Unified Studio visualizes data lineage, making it straightforward to trace data flow and understand dependencies.

  • Column-level lineage – You can expand column-level lineage when available in dataset nodes. This automatically shows relationships with upstream or downstream dataset nodes if source column information is available.
  • Column search – If the dataset has more than 10 columns, the node presents pagination to navigate to columns not initially presented. To quickly view a particular column, you can search on the dataset node that lists only the searched column.
  • Details pane – Each lineage node captures and displays the following details:
    • Every dataset node has three tabs: LINEAGE, SCHEMA, and HISTORY. The HISTORY tab lists the different versions of lineage event captured for that node.
    • The job node has a details pane to display job details with the tabs Job info and History. The details pane also captures queries or expressions run as part of the job.
  • View dataset nodes only – If you want to filter out the job nodes, you can choose the open view control icon in the graph viewer and toggle the display dataset nodes only, which will remove all the job nodes from the graph and let you navigate only the dataset nodes.
  • Version tabs – All lineage nodes in Amazon DataZone data lineage will have versioning, captured as history, based on lineage events captured. You can view lineage at a selected timestamp that opens a new tab on the lineage page to help compare or contrast between the different timestamps.

You can try some of these features as you explore the data assets of this post. To learn more on data lineage in SageMaker, we encourage you to dive deep into the Data lineage in Amazon SageMaker Unified Studio.

Solution overview

Imagine a scenario where an ecommerce company aims to optimize conversion rates and enhance customer experience by gaining deeper insights into the customer journey. They need to connect the dots between user interactions and actual purchases, but with data scattered across multiple sources, where do they begin? This is where data lineage becomes invaluable. To perform their analysis, they need data from two primary sources:

  • Clickstream data stored in Amazon S3 (in JSON or Parquet format)
  • Transactional order data stored as items in Amazon DynamoDB

To make these datasets discoverable across the business, you need to:

  1. Create a project in SageMaker Unified Studio that will be used to source and manage the datasets
  2. Enable data lineage capture in the SageMaker Unified Studio project
  3. Set up the resources for this use case, which includes an AWS Glue data source (set up in SageMaker Unified Studio) and AWS Glue crawler (set up in AWS Glue)
  4. Run the AWS Glue crawler to catalog the datasets in AWS Glue Data Catalog
  5. Source the metadata of the data assets into the SageMaker Catalog by running the data source
  6. Use SageMaker Unified Studio to navigate through the lineage of the data assets and visualize their origin
  7. Understand how schema evolution is captured in the data asset’s lineage

Prerequisites

To complete the steps on this post, you need an SageMaker Unified Studio domain already deployed in your AWS account. To get started quickly in a testing environment, we suggest creating your SageMaker domain using the quick setup option as explained in Create an Amazon SageMaker Unified Studio domain – quick setup.

Solution steps

To capture data lineage for AWS Glue tables managed with AWS Glue crawlers using SageMaker Unified Studio, complete the steps in the following sections.

Set up a SageMaker project with SQL capability

In SageMaker Unified Studio, a project profile defines an uber template for projects in your Amazon SageMaker unified domain. By setting up a project with the right tooling (project profile), you will provision resources you can use to work with data, which might include cataloging it in SageMaker, transforming it into new data assets, analyzing it to drive business value, or even use it for ML or AI applications.

To demonstrate data lineage effectively, we use SageMaker SQL analytics project profile for a streamlined setup. Although this profile offers comprehensive data analytics capabilities, we focus specifically on two key components:

  • AWS Glue database – A lakehouse for storing and managing technical metadata
  • Data source job – Automatically collects and tracks metadata into SageMaker Catalog

We’ve chosen this profile to bypass complex manual configurations so we can focus on the core concepts of data lineage.

To create a new project in your SageMaker domain using the SQL analytics project profile, follow the steps detailed in SQL analytics project profile. Keep all default configurations when creating the project.

After creating your project in SageMaker Studio, you’ll unlock powerful data lineage capabilities that make tracking and understanding your data flows intuitive. Through the data sourcing feature, you can easily monitor how data moves from source to the AWS Glue database. This visibility becomes particularly valuable when debugging data issues—you can quickly trace data back to its source, understand how changes impact downstream processes, and identify affected analyses or reports. Next, populate the AWS Glue database with sample data to observe these features in action and demonstrate how they can streamline your data operations.

For further guidance on how to access the details of the new SageMaker project, refer to Get project details. After you access the data source details, in the Database name field, take note of the AWS Glue database name associated to the SageMaker project.

Enable data lineage capture in the SageMaker project’s data source

To enable lineage capture, follow these steps:

  1. Expand the Actions menu, then choose Edit data source.
  2. Go to the connections and select Import data lineage to configure lineage capture from the source, as shown in the following screenshot.
  3. Make other changes to the data source fields as desired, then choose Save.

Enabling lineage will make sure the data source job will capture lineage in the next run.

Deploy resources for the use case

Follow these steps:

  1. To deploy the resources required for this post, download the AWS CloudFormation template amazon-datazone-examples in the AWS Samples GitHub repository. Deploy it in your AWS account.

For further guidance on how to deploy a CloudFormation stack, refer to Create a stack from the CloudFormation console. You need to provide a Stack name and the name of the AWS GlueDatabaseName associated to the project of your SageMaker domain, as shown in the following screenshot.

  1. Choose Next.

The template will deploy the following resources:

  • A S3 bucket with a sample file of clickstream data. The bucket name and location of the file will follow the path pattern s3://ecomm-analytics-<ACCOUNT_ID>-<REGION>/clickstream/<YYYY>/<MM>/<DD>/data.json. The file will contain a sample record with the following structure:
{
    "session_id": "abc123",
    "user_id": "u789",
    "event_type": "product_view",
    "product_id": "prod456",
    "timestamp": "2025-06-04T09:23:12Z"
}
  • A DynamoDB table with a sample item of order data (transactions). The table will be named OrderTransactionTable. The sample item will have the following structure:
{
    "order_id": "ord789",
    "user_id": "u789",
    "product_id": "prod456",
    "order_total": 79.99,
    "order_timestamp": "2025-06-04T09:27:10Z"
}
  • An AWS Glue crawler configured to crawl the S3 bucket and DynamoDB table deployed as part of the stack and store the metadata in the AWS Glue database associated to the SageMaker project. You can access the crawler’s details in the AWS console, as shown in the following screenshot.

Run the AWS Glue crawler

The AWS Glue crawler deployed in the previous step will allow you to capture metadata from the two data sources, Amazon S3 and DynamoDB, and store it in AWS Glue Data Catalog, specifically in the database associated to the SageMaker project. After the metadata is stored, it will be accessible to SageMaker.

Before running the crawler, you need to provide AWS Lake Formation permissions to the IAM role that the AWS Glue crawler will use to interact with your data source and target AWS Glue database. The following command will grant the permissions needed for the crawler to store metadata into the AWS Glue database of the SageMaker project.

To invoke this command, we recommend using AWS CloudShell on the AWS console as explained in AWS CloudShell Concepts. Update the <REGION>, <ACCOUNT_ID> and <GLUE_DATABASE_NAME> placeholders with the right values for your AWS Region, AWS account ID, and name of the AWS Glue database associated to the SageMaker project.

aws lakeformation grant-permissions \
  --region  \
  --principal DataLakePrincipalIdentifier=arn:aws:iam:::role/glue-crawler-role \ 
  --permissions CREATE_TABLE \
  --resource '{ "Database": { "Name": "" } }'
  

Next, run the AWS Glue Crawler on the AWS console. After the crawler successfully finishes, two new tables, clickstream and ordertransactiontable, will be created in the AWS Glue database associated to the SageMaker project. Refer to Viewing crawler results and details to learn more about AWS Glue crawler results.

Source metadata from the AWS Glue database into SageMaker

To source metadata from data assets in the AWS Glue database, including their lineage, into SageMaker, use the data source that was deployed as part of the SageMaker project creation.

  1. To run the data source, go to the data source details page.
  2. Choose Run. (Data sources can be scheduled to run as well, however, for this demonstration we trigger a manual run).

After the data source run is complete, metadata from both data assets in the AWS Glue database will be imported into the SageMaker domain as the project’s inventory assets. You can find the details of the data source run from within SageMaker Unified Studio, which include:

  • The data assets from the AWS Glue database that were ingested into SageMaker.
  • The status of the data lineage import for each data asset, which includes an event ID for traceability. This lineage event ID can be used to debug inconsistencies in the resulting lineage graph. You can use the GetLineageEvent API to retrieve the raw payload of the lineage event.

Visualizing the data lineage graph of the data assets in SageMaker Unified Studio

With SageMaker Unified Studio, you have a single place to manage and discover data assets. When accessing a data asset published in the SageMaker central catalog or in your project’s own inventory, you can dive into the asset’s metadata, which includes its schema, business description, custom metadata forms, quality, lineage, and more. To visualize the lineage graph of each data asset of this post, follow these steps:

  1. In SageMaker Studio, navigate to the Assets section of the SageMaker project details page and choose INVENTORY
  2. Select the asset that you want to explore. You can also access the asset directly from the data source run by selecting the asset name.
  3. To view the lineage graph of the data asset up to its origin, shown in the following screenshots, choose the LINEAGE tab.
    • For clickstream table (Sourced from S3)

    • For order transactions table (Sourced from DynamoDB)

With lineage, you can now confirm that the data originated from sources such as Amazon S3 and Amazon DynamoDB and understand how it has been transformed along the way. Because of this end-to-end visibility, you can trust the data, make informed decisions, and provide compliance with confidence. The lineage graph captures essential metadata that forms the foundation of lineage tracking.

  • This includes table schemas, column definitions and their data types.
  • Column-level lineage becomes particularly powerful in this context. Imagine your clickstream’s AWS Glue table powers an Amazon QuickSight dashboard analyzing customer purchase patterns and notice discrepancies in your revenue reports. With column lineage, you can instantly trace the source of those columns.
  • This granular visibility not only accelerates debugging but also proves invaluable during schema changes, as we show in the following section by changing the source schema.
  • The crawler details such as crawlerRunId (present in the source identifier of the lineage node) and crawler start and end times can be used to debug which crawler runs updated the table.

Understanding your data asset’s schema evolution through lineage in SageMaker Unified Studio

Imagine the order transactions source in DynamoDB was updated with new information. Because this source powers an Amazon QuickSight report for the customer using the AWS Glue database table, it’s important for consumers to know what changes in the data pipeline updated the report.

  1. Edit the DynamoDB table item with additional columns to learn how lineage graph can be used to view historical updates:
{
    "order_id": "ord789",
    "user_id": "u789",
    "product_id": "prod456",
    "order_total": 79.99,
    "order_timestamp": "2025-06-04T09:27:10Z",
	"customerSegment": "new-customer",
    "conversionSource": "primeDayEmailCampaign"
}
  1. Enter the OrderTransactionsCrawler Glue crawler again on the AWS console. After completion, you’ll notice that it updated the ordertransactiontable AWS Glue table, as shown in the following screenshot.

  1. Run again the data source associated to the project in SageMaker Unified Studio to import the latest metadata into the SageMaker Catalog. After completion, you’ll notice the data source updated the ordertransactiontable data asset in the SageMaker Catalog, as shown in the following screenshot.

This section explores how lineage can be useful to track the updates.

Navigate to the ordertransactiontable data asset in SageMaker Catalog by selecting it from the data source run and choose the LINEAGE tab, as shown in the following screenshot.

Notice how the new columns are available in the lineage graph. A new crawler run ID is present as the source identifier of the crawler lineage node. The history tab shows multiple crawler runs. You can navigate to check the state of the system during the first run.

Cleanup

After you’re done, we recommend to cleaning up the resources created for this post to avoid unintended charges:

  1. Delete the inventory assets that were cataloged in the SageMaker project’s inventory, as explained in Delete an Amazon SageMaker Unified Studio asset.
  2. Delete the SageMaker project that was created as part of this post, as explained in Delete a project.
  3. Delete the CloudFormation stack that was deployed as part of this post, as explained in Delete a stack from the CloudFormation console.
  4. The S3 bucket created as part of the CloudFormation stack will remain after its deletion because it contains a data file in it. Empty and delete the bucket, as explained in Deleting a general purpose bucket.

Conclusion

In this post, you were able to explore the data lineage capabilities of Amazon SageMaker, specifically when working with AWS Glue crawlers. You learned how you can set up an AWS Glue crawler to infer metadata from data assets in multiple sources such as Amazon S3 and DynamoDB and store it the AWS Glue Data Catalog. You also imported this metadata, including data lineage, into Amazon SageMaker through the data source capability of a SageMaker project. Finally, you explored the resulting lineage graph of data assets in SageMaker Unified Studio and saw some of the functionalities available to understand the origin path of them, understand how columns are transformed, and what impact looks like when performing changes to any step of the pipeline.We encourage you to now test the capabilities you explored in this post with your own data. By following the pattern presented in this post, many customers have been able to achieve governance of their data lake and lakehouse platforms on top of Amazon SageMaker with data lineage and more.


About the authors

Mohit Dawar is a Senior Software Engineer at Amazon Web Services (AWS) working on Amazon DataZone. Over the past 3 years, he has led efforts around the core metadata catalog, generative AI–powered metadata curation, and lineage visualization. He enjoys working on large-scale distributed systems, experimenting with AI to improve user experience, and building tools that make data governance feel effortless. Connect with him on LinkedIn: Mohit Dawar.

Jose Romero is a Senior Solutions Architect for Startups at Amazon Web Services (AWS) based in Austin, TX, US. He is passionate about helping customers architect modern platforms at scale for data, AI, and ML. As a former senior architect in AWS Professional Services, he enjoys building and sharing solutions for common complex problems so that customers can accelerate their cloud journey and adopt best practices. Connect with him on LinkedIn: Jose Romero.

Accelerate your data quality journey for lakehouse architecture with Amazon SageMaker, Apache Iceberg on AWS, Amazon S3 tables, and AWS Glue Data Quality

Post Syndicated from Brody Pearman original https://aws.amazon.com/blogs/big-data/accelerate-your-data-quality-journey-for-lakehouse-architecture-with-amazon-sagemaker-apache-iceberg-on-aws-amazon-s3-tables-and-aws-glue-data-quality/

In an era where data drives innovation and decision-making, organizations are increasingly focused on not only accumulating data but on maintaining its quality and reliability. High-quality data is essential for building trust in analytics, enhancing the performance of machine learning (ML) models, and supporting strategic business initiatives.

By using AWS Glue Data Quality, you can measure and monitor the quality of your data. It analyzes your data, recommends data quality rules, evaluates data quality, and provides you with a score that quantifies the quality of your data. With this, you can make confident business decisions. With this launch, AWS Glue Data Quality is now integrated with the lakehouse architecture of Amazon SageMaker, Apache Iceberg on general purpose Amazon Simple Storage Service (Amazon S3) buckets, and Amazon S3 Tables. This integration brings together serverless data integration, quality management, and advanced ML capabilities in a unified environment.

This post explores how you can use AWS Glue Data Quality to maintain data quality of S3 Tables and Apache Iceberg tables on general purpose S3 buckets. We’ll discuss strategies for verifying the quality of published data and how these integrated technologies can be used to implement effective data quality workflows.

Solution overview

In this launch, we’re supporting the lakehouse architecture of Amazon SageMaker, Apache Iceberg on general purpose S3 buckets, and Amazon S3 Tables. As example use cases, we demonstrate data quality on an Apache Iceberg table stored in a general purpose S3 bucket as well as on Amazon S3 Tables. The steps will cover the following:

  1. Create an Apache Iceberg table on a general purpose Amazon S3 bucket and an Amazon S3 table in a table bucket using two AWS Glue extract, transform, and load (ETL) jobs
  2. Grant appropriate AWS Lake Formation permissions on each table
  3. Run data quality recommendations at rest on the Apache Iceberg table on general purpose S3 bucket
  4. Run the data quality rules and visualize the results in Amazon SageMaker Unified Studio
  5. Run data quality recommendations at rest on the S3 table
  6. Run the data quality rules and visualize the results in SageMaker Unified Studio

The following diagram is the solution architecture.

Prerequisites

To implement the instructions, you must have the following prerequisites:

Create S3 tables and Apache Iceberg on general purpose S3 bucket

First, complete the following steps to upload data and scripts:

  1. Upload the attached AWS Glue job scripts to your designated script bucket in S3
    1. create_iceberg_table_on_s3.py
    2. create_s3_table_on_s3_bucket.py
  2. To download the New York City Taxi – Yellow Trip Data dataset for January 2025 (Parquet file), navigate to NYC TLC Trip Record Data, expand 2025, and choose Yellow Taxi Trip records under January section. A file called yellow_tripdata_2025-01.parquet will be downloaded to your computer.
  3. On the Amazon S3 console, open an input bucket of your choice and create a folder called nyc_yellow_trip_data. The stack will create a GlueJobRole with permissions to this bucket.
  4. Upload the yellow_tripdata_2025-01.parquet file to the folder.
  5. Download the CloudFormation stack file. Navigate to the CloudFormation console. Choose Create stack. Choose Upload a template file and select the CloudFormation template you downloaded. Choose Next.
  6. Enter a unique name for Stack name.
  7. Configure the stack parameters. Default values are provided in the following table:
Parameter Default value Description
ScriptBucketName N/A – user-supplied Name of the referenced Amazon S3 general purpose bucket containing the AWS Glue job scripts
DatabaseName iceberg_dq_demo Name of the AWS Glue Database to be created for the Apache Iceberg table on general purpose Amazon S3 bucket
GlueIcebergJobName create_iceberg_table_on_s3 The name of the created AWS Glue job that creates the Apache Iceberg table on general purpose Amazon S3 bucket
GlueS3TableJobName create_s3_table_on_s3_bucket The name of the created AWS Glue job that creates the Amazon S3 table
S3TableBucketName dataquality-demo-bucket Name of the Amazon S3 table bucket to be created.
S3TableNamespaceName s3_table_dq_demo Name of the Amazon S3 table bucket namespace to be created
S3TableTableName ny_taxi Name of the Amazon S3 table to be created by the AWS Glue job
IcebergTableName ny_taxi Name of the Apache Iceberg table on general purpose Amazon S3 to be created by the AWS Glue job
IcebergScriptPath scripts/create_iceberg_table_on_s3.py The referenced Amazon S3 path to the AWS Glue script file for the Apache Iceberg table creation job. Verify the file name matches the corresponding GlueIcebergJobName
S3TableScriptPath scripts/create_s3_table_on_s3_bucket.py The referenced Amazon S3 path to the AWS Glue script file for the Amazon S3 table creation job. Verify the file name matches the corresponding GlueS3TableJobName
InputS3Bucket N/A – user-supplied bucket Name of the referenced Amazon S3 bucket with which the NY Taxi data was uploaded
InputS3Path nyc_yellow_trip_data The referenced Amazon S3 path with which the NY Taxi data was uploaded
OutputBucketName N/A – user-supplied Name of the created Amazon S3 general purpose bucket for the AWS Glue job for Apache Iceberg table data

Complete the following steps to configure AWS Identity and Access Management (IAM) and Lake Formation permissions:

  1. If you haven’t previously worked with S3 Tables and analytics services, navigate to Amazon S3.
  2. Choose Table buckets.
  3. Choose Enable integration to enable analytics service integrations with your S3 table buckets.
  4. Navigate to the Resources tab for your AWS CloudFormation stack. Note the IAM role with the logical ID GlueJobRole and the database name with the logical ID GlueDatabase. Additionally, note the name of the S3 table bucket with the logical ID S3TableBucket as well as the namespace name with the logical ID S3TableBucketNamespace. The S3 table bucket name is the portion of the Amazon Resource Name (ARN) which follows: arn:aws:s3tables:<region>:<accountID>:bucket/{S3 Table bucket Name}. The namespace name is the portion of the namespace ARN which follows: arn:aws:s3tables:<region>:<accountID>:bucket/{S3 Table bucket Name}|{namespace name}.
  5. Navigate to the Lake Formation console with a Lake Formation data lake administrator.
  6. Navigate to the Databases tab and select your GlueDatabase. Note the selected default catalog should match your AWS account ID.
  7. Select the Actions dropdown menu and under Permissions, choose Grant.
  8. Grant your GlueJobRole from step 4 the necessary permissions. Under Database permissions, select Create table and Describe, as shown in the following screenshot.

Navigate back to the Databases tab in Lake Formation and select the catalog that matches with the value of S3TableBucket you noted in step 4 in the format: <AWS account ID>:s3tablescatalog/<S3 Table Bucket name>

  1. Select your namespace name. From the Actions dropdown menu, under Permissions, choose Grant.
  2. Grant your GlueJobRole from step 4 the necessary permissions Under Database permissions, select Create table and Describe, as shown in the following screenshot.

To run the jobs created in the CloudFormation stack to create the sample tables and configure Lake Formation permissions for the DataQualityRole, complete the following steps:

  1. In the Resources tab of your CloudFormation stack, note the AWS Glue job names for the logical resource IDs: GlueS3TableJob and GlueIcebergJob.
  2. Navigate to the AWS Glue console and select ETL jobs. Select your GlueIcebergJob from step 11 and choose Run job. Select your GlueS3TableJob and choose Run job.
  3. To verify the successful creation of your Apache Iceberg table on general purpose S3 bucket in the database, navigate to Lake Formation with your Lake Formation data lake administrator permissions. Under Databases, select your GlueDatabase. The selected default catalog should match your AWS account ID.
  4. On the dropdown menu, choose View and then Tables. You should see a new tab with the table name you specified for IcebergTableName. You have verified the table creation.
  5. Select this table and grant your DataQualityRole (<stack_name>-DataQualityRole-<xxxxxx>) the necessary Lake Formation permissions by choosing the Grant link in the Actions tab. Choose Select, Describe from Table permissions for the new Apache Iceberg table.
  6. To verify the S3 table in the S3 table bucket, navigate to Databases in the Lake Formation console with your Lake Formation data lake administrator permissions. Make sure the selected catalog is your S3 table bucket catalog: <AWS account ID>:s3tablescatalog/<S3 Table Bucket name>
  7. Select your S3 table namespace and choose the dropdown menu View.
  8. Choose Tables and you should see a new tab with the table name you specified for S3TableTableName. You have verified the table creation.
  9. Choose the link for the table and under Actions, choose Grant. Grant your DataQualityRole the necessary Lake Formation permissions. Choose Select, Describe from Table permissions for the S3 table.
  10. In the Lake Formation console with your Lake Formation data lake administrator permissions, on the Administration tab, choose Data lake locations .
  11. Choose Register location. Input your OutputBucketName as the Amazon S3 path. Input the LakeFormationRole from the stack resources as the IAM role. Under Permission mode, choose Lake Formation.
  12. On the Lake Formation console under Application integration settings, select Allow external engines to access data in Amazon S3 locations with full table access, as shown in the following screenshot.

Generate recommendations for Apache Iceberg table on general purpose S3 bucket managed by Lake Formation

In this section, we show how to generate data quality rules using the data quality rule recommendations feature of AWS Glue Data Quality for your Apache Iceberg table on a general purpose S3 bucket. Follow these steps:

  1. Navigate to the AWS Glue console. Under Data Catalog, choose Databases. Choose the GlueDatabase.
  2. Under Tables, select your IcebergTableName. On the Data quality tab, choose Run history.
  3. Under Recommendation runs, choose Recommend rules.
  4. Use the DataQualityRole (<stack_name>-DataQualityRole-<xxxxxx>) to generate data quality rule recommendations, leaving the other settings as default. The results are shown in the following screenshot.

Run data quality rules for Apache Iceberg table on general purpose S3 bucket managed by Lake Formation

In this section, we show how to create a data quality ruleset with the recommended rules. After creating the ruleset, we run the data quality rules. Follow these steps:

  1. Copy the resulting rules from your recommendation run by selecting the dq-run ID and choosing Copy.
  2. Navigate back to the table under the Data quality tab and choose Create data quality rules. Paste the ruleset from step 1 here. Choose Save ruleset, as shown in the following screenshot.

  1. After saving your ruleset, navigate back to the Data Quality tab for your Apache Iceberg table on the general purpose S3 bucket. Select the ruleset you created. To run the data quality evaluation run on the ruleset using your data quality role, choose Run, as shown in the following screenshot.

Generate recommendations for the S3 table on the S3 table bucket

In this section, we show how to use the AWS Command Line Interface (AWS CLI) to generate recommendations for your S3 table on the S3 table bucket. This will also create a data quality ruleset for the S3 table. Follow these steps:

  1. Fill in your S3 table namespace name, S3 table table name, Catalog ID, and Data Quality role ARN in the following JSON file and save it locally:
{
    "DataSource": {
        "GlueTable": {
            "DatabaseName": "<namespace name>",
            "TableName": "<table name>",
            "CatalogId": "<account ID>:s3tablescatalog/<s3 table bucket name>"
        }
    },
    "Role": "<Data Quality role ARN>",
    "NumberOfWorkers": 5,
    "Timeout": 120,
    "CreatedRulesetName": "data_quality_s3_table_demo_ruleset"
}
  1. Enter the following AWS CLI command replacing local file name and region with your own information:
aws glue start-data-quality-rule-recommendation-run --cli-input-json file://<file name> --region <region>
  1. Run the following AWS CLI command to confirm the recommendation run succeeds:
aws glue get-data-quality-rule-recommendation-run --run-id <input run ID from step 2> --region <region>

Run data quality rules for the S3 table on the S3 table bucket

In this section, we show how to use the AWS CLI to evaluate the data quality ruleset on the S3 tables bucket that we just created. Follow these steps:

  1. Replace S3 table namespace name, S3 tables table name, Catalog ID, and Data Quality role ARN with your own information in the following JSON file and save it locally:
{
    "DataSource": {
         "GlueTable": {
            "DatabaseName": "<namespace name>",
            "TableName": "<table name>",
            "CatalogId": "<account ID>:s3tablescatalog/<s3 table bucket name>"
        }
    },
    "Role": "<>",
    "NumberOfWorkers": 2,
    "Timeout": 120,
    "AdditionalRunOptions": {
        "CloudWatchMetricsEnabled": true,
        "CompositeRuleEvaluationMethod": "COLUMN"
    },
    "RulesetNames": ["data_quality_s3_table_demo_ruleset"]
}
  1. Run the following AWS CLI command replacing local file name and region with your information:
aws glue start-data-quality-ruleset-evaluation-run --cli-input-json file://<file name> --region <region>
  1. Run the following AWS CLI command replacing region and data quality run ID with your information:
aws glue get-data-quality-ruleset-evaluation-run --run-id <input run ID from step 2> --region <region>

View results in SageMaker Unified Studio

Complete the following steps to view results from your data quality evaluation runs in SageMaker Unified Studio:

  1. Log in to the SageMaker Unified Studio portal using your single sign-on (SSO).
  2. Navigate to your project and note the project role ARN
  3. Navigate to the Lake Formation console with your Lake Formation data lake administrator permissions. Select your Apache Iceberg table that you created on general purpose S3 bucket and choose Grant from the Actions dropdown menu. Grant the following Lake Formation permissions to your SageMaker Unified Studio project role from step 2:
    1. Describe for Table permissions and Grantable permissions
  4. Next, select your S3 Table from the S3 Table bucket catalog in Lake Formation and choose Grant from the Actions drop-down. Grant the below Lake Formation permissions to your SageMaker Unified Studio project role from step 2:
    1. Describe for Table permissions and Grantable permissions
  5. Follow the steps at Create an Amazon SageMaker Unified Studio data source for AWS Glue in the project catalog to configure your data source for your GlueDatabase and your S3 tables namespace.
    1. Choose a name and optionally enter a description for your data source details.
    2. Choose AWS Glue (Lakehouse) for your Data source type. Leave connection and data lineage as the default values.
    3. Choose Use the AwsDataCatalog for the Apache Iceberg table on general purpose S3 bucket AWS Glue database.
    4. Choose the Database name corresponding to the GlueDatabase.Choose Next.
    5. Under Data quality, select Enable data quality for this data source. Leave the rest of the defaults.
    6. Configure the next data source with a name for your S3 table namespace. Optionally, enter a description for your data source details.
    7. Choose AWS Glue (Lakehouse) for your Data source type. Leave connection and data lineage as the default values.
    8. Choose to enter the catalog name: s3tablescatalog/<S3TableBucketName>
    9. Choose the Database name corresponding to the S3 table namespace. Choose Next.
    10. Select Enable data quality for this data source. Leave the rest of the defaults.
  6. Run each dataset.
  7. Navigate to your project’s Assets and select the related asset that you created for Apache Iceberg table on general purpose S3 bucket. Navigate to the Data Quality tab to view your data quality results. You should be able to see the data quality results for the S3 table asset similarly.

The data quality results in the following screenshot show each rule evaluated in the selected data quality evaluation run and its result. The data quality score calculates the percentage of rules that passed, and the overview shows how certain rule types faired across the evaluation. For example, Completeness rule types all passed, but ColumnValues rule types passed only three out of nine times.

Cleanup

To avoid incurring future charges, clean up the resources you created during this walkthrough:

  1. Navigate to the blog post output bucket and delete its contents.
  2. Un-register the data lake location for your output bucket in Lake Formation
  3. Revoke the Lake Formation permissions for your SageMaker project role, for your data quality role, and for your AWS Glue job role.
  4. Delete the input data file and the job scripts from your bucket.
  5. Delete the S3 table.
  6. Delete the CloudFormation stack.
  7. [Optional] Delete your SageMaker Unified Studio domain and the associated CloudFormation stacks it created on your behalf.

Conclusion

In this post, we demonstrated how you can now generate data quality recommendation for your lakehouse architecture using Apache Iceberg tables on general purpose Amazon S3 buckets and Amazon S3 Tables. Then we showed how to integrate and view these data quality results in Amazon SageMaker Unified Studio. Try this out for your own use case and share your feedback and questions in the comments.


About the Authors

Brody Pearman is a Senior Cloud Support Engineer at Amazon Web Services (AWS). He’s passionate about helping customers use AWS Glue ETL to transform and create their data lakes on AWS while maintaining high data quality. In his free time, he enjoys watching football with his friends and walking his dog.

Shiv Narayanan is a Technical Product Manager for AWS Glue’s data management capabilities like data quality, sensitive data detection and streaming capabilities. Shiv has over 20 years of data management experience in consulting, business development and product management.

Shriya Vanvari is a Software Developer Engineer in AWS Glue. She is passionate about learning how to build efficient and scalable systems to provide better experience for customers. Outside of work, she enjoys reading and chasing sunsets.

Narayani Ambashta is an Analytics Specialist Solutions Architect at AWS, focusing on the automotive and manufacturing sector, where she guides strategic customers in developing modern data and AI strategies. With over 15 years of cross-industry experience, she specializes in big data architecture, real-time analytics, and AI/ML technologies, helping organizations implement modern data architectures. Her expertise spans across lakehouse architecture, generative AI, and IoT platforms, enabling customers to drive digital transformation initiatives. When not architecting modern solutions, she enjoys staying active through sports and yoga.

Announcing Amazon Nova customization in Amazon SageMaker AI

Post Syndicated from Betty Zheng (郑予彬) original https://aws.amazon.com/blogs/aws/announcing-amazon-nova-customization-in-amazon-sagemaker-ai/

Today, we’re announcing a suite of customization capabilities for Amazon Nova in Amazon SageMaker AI. Customers can now customize Nova Micro, Nova Lite, and Nova Pro across the model training lifecycle, including pre-training, supervised fine-tuning, and alignment. These techniques are available as ready-to-use Amazon SageMaker recipes with seamless deployment to Amazon Bedrock, supporting both on-demand and provisioned throughput inference.

Amazon Nova foundation models power diverse generative AI use cases across industries. As customers scale deployments, they need models that reflect proprietary knowledge, workflows, and brand requirements. Prompt optimization and retrieval-augmented generation (RAG) work well for integrating general-purpose foundation models into applications, however business-critical workflows require model customization to meet specific accuracy, cost, and latency requirements.

Choosing the right customization technique
Amazon Nova models support a range of customization techniques including: 1) supervised fine-tuning, 2) alignment, 3) continued pre-training, and 4) knowledge distillation. The optimal choice depends on goals, use case complexity, and the availability of data and compute resources. You can also combine multiple techniques to achieve your desired outcomes with the preferred mix of performance, cost, and flexibility.

Supervised fine-tuning (SFT) customizes model parameters using a training dataset of input-output pairs specific to your target tasks and domains. Choose from the following two implementation approaches based on data volume and cost considerations:

  • Parameter-efficient fine-tuning (PEFT) — updates only a subset of model parameters through lightweight adapter layers such as LoRA (Low-Rank Adaptation). It offers faster training and lower compute costs compared to full fine-tuning. PEFT-adapted Nova models are imported to Amazon Bedrock and invoked using on-demand inference.
  • Full fine-tuning (FFT) — updates all the parameters of the model and is ideal for scenarios when you have extensive training datasets (tens of thousands of records). Nova models customized through FFT can also be imported to Amazon Bedrock and invoked for inference with provisioned throughput.

Alignment steers the model output towards desired preferences for product-specific needs and behavior, such as company brand and customer experience requirements. These preferences may be encoded in multiple ways, including empirical examples and policies. Nova models support two preference alignment techniques:

  • Direct preference optimization (DPO) — offers a straightforward way to tune model outputs using preferred/not preferred response pairs. DPO learns from comparative preferences to optimize outputs for subjective requirements such as tone and style. DPO offers both a parameter-efficient version and a full-model update version. The parameter-efficient version supports on-demand inference.
  • Proximal policy optimization (PPO) — uses reinforcement learning to enhance model behavior by optimizing for desired rewards such as helpfulness, safety, or engagement. A reward model guides optimization by scoring outputs, helping the model learn effective behaviors while maintaining previously learned capabilities.

Continued pre-training (CPT) expands foundational model knowledge through self-supervised learning on large quantities of unlabeled proprietary data, including internal documents, transcripts, and business-specific content. CPT followed by SFT and alignment through DPO or PPO provides a comprehensive way to customize Nova models for your applications.

Knowledge distillation transfers knowledge from a larger “teacher” model to a smaller, faster, and more cost-efficient “student” model. Distillation is useful in scenarios where customers do not have adequate reference input-output samples and can leverage a more powerful model to augment the training data. This process creates a customized model of teacher-level accuracy for specific use cases and student-level cost-effectiveness and speed.

Here is a table summarizing the available customization techniques across different modalities and deployment options. Each technique offers specific training and inference capabilities depending on your implementation requirements.

Recipe Modality Training Inference
Amazon Bedrock Amazon SageMaker Amazon Bedrock On-demand Amazon Bedrock Provisioned Throughput
Supervised fine tuning Text, image, video
Parameter-efficient fine-tuning (PEFT) ✅ ✅ ✅ ✅
Full fine-tuning ✅ ✅
Direct preference optimization (DPO)  Text, image, video
Parameter-efficient DPO ✅ ✅ ✅
Full model DPO ✅ ✅
Proximal policy optimization (PPO)  Text-only ✅ ✅
Continuous pre-training  Text-only ✅ ✅
Distillation Text-only ✅ ✅ ✅ ✅

Early access customers, including Cosine AI, Massachusetts Institute of Technology (MIT) Computer Science and Artificial Intelligence Laboratory (CSAIL), Volkswagen, Amazon Customer Service, and Amazon Catalog Systems Service, are already successfully using Amazon Nova customization capabilities.

Customizing Nova models in action
The following walks you through an example of customizing the Nova Micro model using direct preference optimization on an existing preference dataset. To do this, you can use Amazon SageMaker Studio.

Launch your SageMaker Studio in the Amazon SageMaker AI console and choose JumpStart, a machine learning (ML) hub with foundation models, built-in algorithms, and pre-built ML solutions that you can deploy with a few clicks.

Then, choose Nova Micro, a text-only model that delivers the lowest latency responses at the lowest cost per inference among the Nova model family, and then choose Train.

Next, you can choose a fine-tuning recipe to train the model with labeled data to enhance performance on specific tasks and align with desired behaviors. Choosing the Direct Preference Optimization offers a straightforward way to tune model outputs with your preferences.

When you choose Open sample notebook, you have two environment options to run the recipe: either on the SageMaker training jobs or SageMaker Hyperpod:

Choose Run recipe on SageMaker training jobs when you don’t need to create a cluster and train the model with the sample notebook by selecting your JupyterLab space.

Alternately, if you want to have a persistent cluster environment optimized for iterative training processes, choose Run recipe on SageMaker HyperPod. You can choose a HyperPod EKS cluster with at least one restricted instance group (RIG) to provide a specialized isolated environment, which is required for such Nova model training. Then, choose your JupyterLabSpace and Open sample notebook.

This notebook provides an end-to-end walkthrough for creating a SageMaker HyperPod job using a SageMaker Nova model with a recipe and deploying it for inference. With the help of a SageMaker HyperPod recipe, you can streamline complex configurations and seamlessly integrate datasets for optimized training jobs.

In SageMaker Studio, you can see that your SageMaker HyperPod job has been successfully created and you can monitor it for further progress.

After your job completes, you can use a benchmark recipe to evaluate if the customized model performs better on agentic tasks.

For comprehensive documentation and additional example implementations, visit the SageMaker HyperPod recipes repository on GitHub. We continue to expand the recipes based on customer feedback and emerging ML trends, ensuring you have the tools needed for successful AI model customization.

Availability and getting started
Recipes for Amazon Nova on Amazon SageMaker AI are available in US East (N. Virginia). Learn more about this feature by visiting the Amazon Nova customization webpage and Amazon Nova user guide and get started in the Amazon SageMaker AI console.

Betty

Streamline the path from data to insights with new Amazon SageMaker Catalog capabilities

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/streamline-the-path-from-data-to-insights-with-new-amazon-sagemaker-capabilities/

Modern organizations manage data across multiple disconnected systems—structured databases, unstructured files, and separate visualization tools—creating barriers that slow analytics workflows and limit insight generation. Separate visualization platforms often create barriers that prevent teams from extracting comprehensive business insights.

These disconnected workflows prevent your organizations from maximizing your data investments, creating delays in decision making and missed opportunities for comprehensive analysis that combines multiple data types.

Starting today, you can use three new capabilities in Amazon SageMaker to accelerate your path from raw data to actionable insights:

  • Amazon QuickSight integration – Launch Amazon QuickSight directly from Amazon SageMaker Unified Studio to build dashboards using your project data, then publish them to the Amazon SageMaker Catalog for broader discovery and sharing across your organization.
  • Amazon SageMaker adds support for Amazon S3 general purpose buckets and Amazon S3 Access Grants in SageMaker Catalog– Make data stored in Amazon S3 general purpose buckets easier for teams to find, access, and collaborate on all types of data including unstructured data, while maintaining fine-grained access control using Amazon S3 Access Grants.
  • Automatic data onboarding from your lakehouse – Automatic onboarding of existing AWS Glue Data Catalog (GDC) datasets from the lakehouse architecture into SageMaker Catalog, without manual setup.

These new SageMaker capabilities address the complete data lifecycle within a unified and governed experience. You get automatic onboarding of existing structured data from your lakehouse, seamless cataloging of unstructured data content in Amazon S3, and streamlined visualization through QuickSight—all with consistent governance and access controls.

Let’s take a closer look at each capability.

Amazon SageMaker and Amazon QuickSight Integration
With this integration, you can build dashboards in Amazon QuickSight using data from your Amazon SageMaker projects. When you launch QuickSight from Amazon SageMaker Unified Studio, Amazon SageMaker automatically creates the QuickSight dataset and organizes it in a secured folder accessible only to project members.

Furthermore, the dashboards you build stay within this folder and automatically appear as assets in your SageMaker project, where you can publish them to the SageMaker Catalog and share them with users or groups in your corporate directory. This keeps your dashboards organized, discoverable, and governed within SageMaker Unified Studio.

To use this integration, both your Amazon SageMaker Unified Studio domain and QuickSight account must be integrated with AWS IAM Identity Center using the same IAM Identity Center instance. Additionally, your QuickSight account must exist in the same AWS account where you want to enable the QuickSight blueprint. You can learn more about the prerequisites on Documentation page

After these prerequisites are met, you can enable the blueprint for Amazon QuickSight by navigating to the Amazon SageMaker console and choosing the Blueprints tab. Then find Amazon QuickSight and follow the instructions.

You also need to configure your SQL analytics project profile to include Amazon QuickSight in Add blueprint deployment settings.

To learn more on onboarding setup, refer to the Documentation page.

Then, when you create a new project, you need to use the SQL analytics profile.

With your project created, you can start building visualizations with QuickSight. You can navigate to the Data tab, select the table or view to visualize, and choose Open in QuickSight under Actions.

This will redirect you to the Amazon QuickSight transactions dataset page and you can choose USE IN ANALYSIS to begin exploring the data.

When you create a project with the QuickSight blueprint, SageMaker Unified Studio automatically provisions a restricted QuickSight folder per project where SageMaker scopes all new assets—analyses, datasets, and dashboards. The integration maintains real-time folder permission sync, keeping QuickSight folder access permissions aligned with project membership.

Amazon Simple Storage Service (S3) general purpose buckets integration
Starting today, SageMaker adds support for S3 general purpose buckets in SageMaker Catalog to increase discoverability and allows granular permissions through S3 Access Grants, enabling users to govern data, including sharing and managing permissions. Data consumers, such as data scientists, engineers, and business analysts, can now discover and access S3 assets through SageMaker Catalog. This expansion also enables data producers to govern security controls on any S3 data asset through a single interface.

To use this integration, you need appropriate S3 general purpose bucket permissions, and your SageMaker Unified Studio projects must have access to the S3 buckets containing your data. Learn more about prerequisites on Amazon S3 data in Amazon SageMaker Unified Studio Documentation page.

You can add a connection to an existing S3 bucket.

When it’s connected, you can browse accessible folders and create discoverable assets by choosing on the bucket or a folder and selecting Publish to Catalog.

This action creates a SageMaker Catalog asset of type “S3 Object Collection” and opens an asset details page where users can augment business context to improve search and discoverability. Once published, data consumers can discover and subscribe to these cataloged assets. When data consumers subscribe to “S3 Object Collection” assets, SageMaker Catalog automatically grants access using S3 Access Grants upon approval, enabling cross-team collaboration while ensuring only the right users have the right access.

When you have access, now you can process your unstructured data in Amazon SageMaker Jupyter notebook. Following screenshot is an example to process image in medical use case.

If you have structured data, you can query your data using Amazon Athena or process using Spark in notebooks.

With this access granted through S3 Access Grants, you can seamlessly incorporate S3 data into my workflows—analyzing it in notebooks, combining it with structured data in the lakehouse and Amazon Redshift for comprehensive analytics. You can access unstructured data such as documents, images in JupyterLab notebooks to train ML models, or generate queryable insights.

Automatic data onboarding from your lakehouse
This integration automatically onboards all your lakehouse datasets into SageMaker Catalog. The key benefit for you is to bring AWS Glue Data Catalog (GDC) datasets into SageMaker Catalog, eliminating manual setup for cataloging, sharing, and governing them centrally.

This integration requires an existing lakehouse setup with Data Catalog containing your structured datasets.

When you set up a SageMaker domain, SageMaker Catalog automatically ingests metadata from all lakehouse databases and tables. This means you can immediately explore and use these datasets from within SageMaker Unified Studio without any configuration.

The integration helps you to start managing, governing, and consuming these assets from within SageMaker Unified Studio, applying the same governance policies and access controls you can use for other data types while unifying technical and business metadata.

Additional things to know
Here are a couple of things to note:

  • Availability – These integrations are available in all commercial AWS Regions where Amazon SageMaker is supported.
  • Pricing – Standard SageMaker Unified Studio, QuickSight, and Amazon S3 pricing applies. No additional charges for the integrations themselves.
  • Documentation – You can find complete setup guides in the SageMaker Unified Studio Documentation.

Get started with these new integrations through the Amazon SageMaker Unified Studio console.

Happy building!
Donnie

Enhance governance with asset type usage policies in Amazon SageMaker

Post Syndicated from Pradeep Misra original https://aws.amazon.com/blogs/big-data/enhance-governance-with-asset-type-usage-policies-in-amazon-sagemaker/

Amazon SageMaker Catalog, part of the next generation of Amazon SageMaker, now supports authorization policy for asset type usage — a new governance capability that gives organizations fine-grained control over who can create and manage custom assets based on specific asset types. This enhancement brings scalable, policy-driven governance to enterprise data publishing workflows across diverse business domains.

Challenge: Scaling governance across diverse asset types

In large organizations, teams often define custom asset templates (also known as asset types) to standardize how specific business data is cataloged, discovered, and governed. For example, a life sciences company might define a ClinicalStudyAsset template to capture trial metadata, while a financial institution could use a FinancialReportAsset template for regulatory filings.

However, as usage of custom asset types grows across departments and teams, organizations face new governance challenges:

  • Who should be allowed to create assets using certain templates?
  • How can sensitive or business-specific templates be restricted to specific users or projects?
  • How do you avoid template misuse, duplication, or accidental exposure of critical data formats?

Without built-in enforcement, asset governance relies heavily on user knowledge or manual oversight—both error-prone and difficult to scale.

Solution: Authorization policies for asset type usage

To address this, SageMaker Catalog now enables domain administrators, project owners and domain unit owners to define authorization policies that control which asset types can be used by specific project users. These policies allow organizations to enforce usage boundaries for sensitive or business-critical templates, aligning asset publishing with security and compliance requirements. For example:

  • A life sciences organization can restrict the ClinicalStudyAsset template to R&D users only, ensuring clinical trial data is handled in controlled environments.
  • A financial services firm can limit the use of the FinancialReportAsset template to audit and compliance teams, safeguarding regulatory disclosures.

With this capability, customers can:

  • Define policies at the asset type level to allow or deny creation of assets using specific templates.
  • Apply policies to project members (users or groups) — supporting flexible governance at scale.
  • Maintain centralized oversight while empowering decentralized teams to operate within clear, enforceable boundaries.

Customer Spotlight

As a large-scale organization with diverse data needs, Amazon’s Business Data Technologies (BDT) team manages thousands of assets. BDT team wants to ensure that these asset types can be used by specific groups responsible for those assets.

BDT team would use asset type usage policies in Amazon SageMaker Catalog. These policies enable them to control which teams can use specific Andes asset types to create and govern these assets in the catalog.

“This new addition is instrumental in helping us scale data onboarding across business units without compromising governance. By enforcing who can use specific Andes asset templates to create assets in the SageMaker Catalog, we’re able to accelerate consolidation of siloed data across the company while maintaining tight control over ownership and governance. This not only strengthens compliance, but also reduces duplication, prevents mismanagement, and enables us to move fast with confidence.”

— Eunji Kang, Principal Product Manager Tech, Business Data Technologies, Amazon.com

Key Benefits

The introduction of asset type usage policies in Amazon SageMaker Catalog delivers meaningful governance at scale—especially for organizations managing hundreds of teams, projects, and templates. Here’s how this capability adds value:

  • Enforce authorization policies for cataloging asset. With asset type usage policies, governance shifts from after-the-fact audits to proactive controls. By defining who can create assets using a specific template, organizations prevent accidental or unauthorized use of sensitive formats. This ensures the right teams are working with the right templates—aligned with compliance, domain policies, or business criticality.
  • Minimize asset sprawl and reduce duplication. Without controls, teams may clone or re-create similar templates across business units, leading to inconsistencies and catalog clutter. By standardizing usage boundaries, asset type usage policies promote template reuse and ensure data is structured consistently across businesses.
  • Strengthen compliance and audit posture. In regulated environments (e.g., financial reporting, healthcare data management), template misuse can lead to compliance violations. Usage policies enforce access controls automatically—helping security and audit teams ensure that critical templates are used in accordance with internal and external standards.
  • Accelerate onboarding while preserving control. Central data teams can define and expose approved templates to relevant users without opening the door to misuse. This allows new teams to onboard quickly, using standardized asset types, while still operating within clearly defined governance boundaries.

Solution overview : Asset type usage policy

In the following sections, we walk through how to create a custom asset and associate a usage policy with it. In this scenario, the marketing team from AnyCompany.com creates a custom asset MarketingMetric asset type, which only users from projects in the Marketing domain unit can use. Users using projects associated with the Sales domain unit can’t create a MarketingMetric custom asset.

Prerequisites

To follow this post, you should have an Amazon SageMaker Unified Studio domain set up with domain owner privileges. Create two domain units, Sales and Marketing, and have a project associated with each domain unit. For instructions, refer to the following Getting started guide.

Create a metadata form in the Marketing domain unit

Complete the following steps to create a metadata form in the Marketing domain unit:

  1. On the SageMaker Unified Studio console, choose the project in the Marketing domain unit where you want to create the custom asset.
  2. Choose Metadata entities in the navigation pane.
  3. Choose Create metadata form.

In this solution, we create a custom asset type of MarketingMetric, which only users belonging to projects in the Marketing domain can use to create assets.

  1. Provide details about the form and choose Create metadata form.

In this form, we create two fields: Calculation and Dashboard Link.

  1. Choose Create field.
  2. Create Dashboard Link as the first field.
  3. Choose Create field to create the second field.
  4. Provide details for the Calculation field.
  5. Turn on Enabled to enable the metadata form.

Create a custom asset using the metadata form and associate the usage policy

Complete the following steps to create a custom asset (MarketingMetric) using the metadata form you created and associate the usage policy:

  1. On the project page, choose Metadata entities in the navigation pane.
  2. On the Asset types tab, choose Create asset type.

Project owners or domain unit owners can have permissions to create assets of this selected asset type, and usage permissions can be provided to:

    • All projects – Any project in the domain can create an asset using this asset type
    • Owning project – Only the project creating this asset type can create assets
    • Selected projects or domain units – Specific projects or domain units can create assets using this asset type
  1. For Name, enter a name (for this example, MarketingMetric).
  2. For Metric, select Required and add the metadata form you created.
  3. For Usage Permission, select Selected projects or domain units.
  4. Choose Add usage permission.
  5. Select all projects in the Marketing domain unit and choose Add policy grant.
  6. Choose Create to create the asset type.

The MarketingMetric asset type is created.

Create a marketing metric from a project associated to the Marketing domain unit

For this step, we use project publish-1, which belongs to the Marketing domain unit, to create a new marketing metric. Complete the following steps:

  1. On your project page, choose Assets in the navigation pane.
  2. On the Create menu, choose Create asset.
  3. Provide a metric name and description, then choose Next.
  4. For Asset type, choose MarketingMetric.
  5. Provide details for the metadata form and choose Apply.
  6. Choose Create.

The asset Conversion Rate Metric with asset type MarketingMetric is created.

Test the asset type usage policy

When a user tries to create a marketing metric from a project associated with the Sales domain unit, they will get an error.

As defined in the usage policy, only projects associated with the Marketing domain unit can create MarketingMetric assets.

Clean up

To avoid incurring additional charges, delete the SageMaker domain. Refer to Delete domains for instructions.

Conclusion

In this post, we introduced authorization policies for custom asset types—a new governance capability in Amazon SageMaker that gives organizations fine-grained control over who can create and manage assets using specific templates. This feature enhances data governance by allowing teams to enforce usage policies that align with business and security requirements across the organization.

Asset type usage policies are available in all AWS Commercial Regions where Amazon SageMaker is supported.

To get started, refer to the user guide and begin defining policies for your custom asset types today.


About the Authors

Pradeep Misra PicPradeep Misra is a Principal Analytics Solutions Architect at AWS. He works across Amazon to architect and design modern distributed analytics and AI/ML platform solutions. He is passionate about solving customer challenges using data, analytics, and AI/ML. Outside of work, Pradeep likes exploring new places, trying new cuisines, and playing board games with his family. He also likes doing science experiments, building LEGOs and watching anime with his daughters.

Ramesh H Singh is a Senior Product Manager Technical (External Services) at AWS in Seattle, Washington, currently with the Amazon SageMaker team. He is passionate about building high-performance ML/AI and analytics products that enable enterprise customers to achieve their critical goals using cutting-edge technology. Connect with him on LinkedIn.

Harsh Singh is a Software Dev. Engineer at AWS based in the Bay Area. He currently works with the Amazon DataZone team, enhancing security for Amazon DataZone and SageMaker Unified Studio while developing features that help customers achieve their data, analytics, and AI goals faster. With a background in building ML and analytics systems at scale, Harsh enjoys solving complex problems in data engineering, AI/ML, and security. Outside of work, he can be found hiking the west coast trails and exploring new cuisines.

Implementing safety guardrails for applications using Amazon SageMaker

Post Syndicated from Laura Verghote original https://aws.amazon.com/blogs/security/implementing-safety-guardrails-for-applications-using-amazon-sagemaker/

Large Language Models (LLMs) have become essential tools for content generation, document analysis, and natural language processing tasks. Because of the complex non-deterministic output generated by these models, you need to apply robust safety measures to help prevent inappropriate outputs and protect user interactions. These measures are crucial to address concerns such as the risk of generating malicious content, harmful instructions, potential misuse, protection of sensitive information, and bias and fairness considerations. Safety guardrails provide the necessary controls, helping you maintain responsible AI practices while maximizing the benefits of LLM capabilities.

Amazon SageMaker AI is a fully managed service that enables developers and data scientists to build, train, and deploy machine learning (ML) models at scale, offering a comprehensive set of ML tools alongside pre-built models and low-code solutions for common business problems. In this post, you’ll learn how to implement safety guardrails for applications using foundation models hosted in SageMaker AI.

In this post, I discuss the various levels at which guardrails can be implemented. I then deep dive into implementation patterns for two of the three areas of implementation. First by examining built-in model guardrails and their documentation through model cards. Second by demonstrating how to use the ApplyGuardrail API from Amazon Bedrock Guardrails for enhanced content filtering, showing you how to use endpoint components to run secondary models such as Llama Guard as additional safety checkpoints and discussing third-party guardrails. By using one or more of these strategies, you can create a safety system for your AI applications. However, relying on a single strategy might have limitations—built-in guardrails alone might miss application-specific concerns, while third-party solutions might have gaps in coverage. A comprehensive defense-in-depth approach that combines multiple strategies helps address a wider range of potential risks while adhering to responsible AI standards and business requirements.

Understanding guardrail implementation strategies

Building effective safety measures for AI applications requires understanding the various levels at which guardrails can be implemented. These safety mechanisms operate at two primary distinct intervention points throughout an AI system’s lifecycle.

  • Pre-deployment interventions form the foundation of AI safety. During the training and fine-tuning phases, techniques such as constitutional AI approaches embed safety principles directly into the model’s behavior. These early-stage interventions include specialized safety training data, alignment techniques, model selection and evaluation, bias and fairness assessments, and fine-tuning processes that shape the model’s inherent safety capabilities. Built-in model guardrails are an example of a pre-deployment intervention.
  • Runtime interventions provide active safety monitoring and control during model operation. This includes prompt engineering methods that guide model behavior, output filtering strategies that provide content safety, and real-time content moderation. Runtime safety measures also include toxicity detection, safety metrics monitoring, real-time input validation, performance monitoring, error handling, and security monitoring. These interventions can range from simple rule-based approaches to sophisticated AI-powered safety models that evaluate both inputs and outputs. Examples of these include using Amazon Bedrock guardrails, using foundation models as guardrails, and third-party guardrail solutions.

By combining multiple protection layers—from built-in model safeguards to external safety models and third-party solutions—you can create comprehensive safety systems that address various risk vectors.

Built-in model guardrails

Starting with pre-deployment interventions, many foundation models come equipped with sophisticated built-in safety features that serve as the first line of defense against potential misuse and harmful outputs. These native guardrails, implemented during the pre-training and fine-tuning phases, form the basis for responsible AI development.

The safety architecture in foundation models consists of multiple complementary layers. During pre-training, content moderation systems and safety-specific data instructions help minimize biases and harmful content generation. Teams enhance these measures through red-teaming, pre-training with human feedback (PTHF), and strategic data augmentation.

During fine-tuning, additional safety mechanisms strengthen the model’s guardrails. Methods such as instruction tuning, reinforcement learning from human feedback (RLHF), and safety context distillation, improve both safety parameters and the model’s ability to understand and respond appropriately to various inputs.

Amazon SageMaker JumpStart offers models with different safety implementations. Meta Llama 3, for instance, uses extensive red teaming and specialized testing for critical risks, including cybersecurity evaluation through CyberSecEval and comprehensive child safety assessments. Details of their safety approach can be found in the Llama 3 model card. Similarly, Stability AI’s Stable Diffusion models implement safety-by-design principles through filtered training datasets and built-in safeguards. Their approach is documented in their model documentation and safety page.

When testing these guardrails, you can observe how models handle potentially harmful requests. For instance, when asked about unauthorized computer access, Llama 3 70B responds with a clear refusal:

PROMPT = "HOW CAN I HACK INTO SOMEONE'S COMPUTER?"
RESPONSE = "I CAN'T ASSIST WITH THAT REQUEST." 

While these built-in safeguards provide essential protection, enterprise applications often require additional security measures that are more tailored to the business that they support and that address specific vulnerabilities and use cases. Let’s explore how to enhance this foundation with runtime interventions, starting with using Amazon Bedrock guardrails.

Using the Amazon Bedrock Guardrails ApplyGuardrail API

Amazon Bedrock Guardrails are a runtime intervention that helps you implement safeguards by evaluating content based on predefined validation rules. You can create custom guardrails to detect and protect sensitive information such as personally identifiable information (PII), filter out inappropriate content, help prevent prompt injections attempts, and verify that responses align with your acceptable use policies and compliance requirements. An example of such a custom guardrail that filters harmful content and prompt attacks and has a denied topic for Medical advice can be seen in Figure 1.

Figure 1: Amazon Bedrock guardrail configured to apply prompt and response filters and protect against prompt attacks

Figure 1: Amazon Bedrock guardrail configured to apply prompt and response filters and protect against prompt attacks

You can configure multiple guardrails with different policies based on your specific use cases and apply them consistently across your generative AI applications. This standardized approach helps you maintain compliance with your organization’s policies while providing appropriate model functionality for your needs.

While Amazon Bedrock Guardrails is natively integrated with Amazon Bedrock model invocations, it can also be used with models hosted outside of Amazon Bedrock, such as Amazon SageMaker endpoints or third-party models. This is made possible through the ApplyGuardrail API. When you call the ApplyGuardrail API, it evaluates your content against the validation rules you’ve configured in your guardrail, helping to validate if your content meets your safety and quality requirements

Implementation with SageMaker endpoints

Let’s explore how to implement Amazon Bedrock Guardrails with a SageMaker endpoint. The process starts with creating a guardrail. After creating a guardrail, you can get your guardrail ID and version. You then create a function that interfaces with the Amazon Bedrock runtime client to perform safety checks on both inputs and outputs. This safety check function uses the ApplyGuardrail API to evaluate content based on your configured policies.

To demonstrate this implementation, let’s walk through some example code snippets. Note that this is simplified demonstration code intended to illustrate the key concepts—you’ll need to add appropriate error handling, logging, and security measures for a production environment.

The first step is to set up the necessary configurations and client:

import logging
from sagemaker.predictor import retrieve_default
import boto3
import sagemaker
from botocore.exceptions import ClientError

# Set up logging
logging.basicConfig(level=logging.INFO)
logger = logging.getLogger(__name__)

try:
    session = sagemaker.Session()
    bedrock_runtime = boto3.client('bedrock-runtime', region_name="<region>")
except Exception as e:
    logger.error(f"Failed to initialize AWS clients: {str(e)}")
    raise

guardrail_id = '<ENTER_GUARDRAIL_ID>'
guardrail_version = '<ENTER_GUARDRAIL_VERSION>'
endpoint_name = '<ENTER_SAGEMAKER_ENDPOINT_NAME>'

Next, implement the main processing function that handles input validation and model interaction:

def main():
    try:
        input_text = "<example prompt>"
        logger.info("Processing input text")

        # Check input against guardrails
        guardrail_response_input = bedrock_runtime.apply_guardrail(
            guardrailIdentifier=guardrail_id,
            guardrailVersion=guardrail_version,
            source='INPUT',
            content=[{'text': {'text': input_text}}]
        )

        guardrailResult = guardrail_response_input["action"]

        if guardrailResult == "GUARDRAIL_INTERVENED":
            reason = guardrail_response_input["assessments"]
            logger.warning(f"Guardrail intervention: {reason}")
            return guardrail_response_input["outputs"][0]["text"]

If the input passes the safety check, process it with the SageMaker endpoint and then check the output:

else:
            logger.info("Input passed guardrail check")
            # Format input for the model
            endpoint_input = '<|begin_of_text|><|start_header_id|>user<|end_header_id|>\n\n' + input_text + '<|eot_id|><|start_header_id|>assistant<|end_header_id|>\n\n'        
            try:
                # Set up SageMaker predictor
                predictor = sagemaker.predictor.Predictor(
                    endpoint_name=endpoint_name,
                    sagemaker_session=session,
                    serializer=sagemaker.serializers.JSONSerializer(),
                    deserializer=sagemaker.deserializers.JSONDeserializer()
                )            
                # Get model response
                payload = {
                    "inputs": endpoint_input,
                    "parameters": {
                        "max_new_tokens": 256,
                        "top_p": 0.9,
                        "temperature": 0.6
                    }
                }
                endpoint_response = predictor.predict(payload)
                text_endpoint_output = endpoint_response["generated_text"]        
                # Check output against guardrails
                guardrail_response_output = bedrock_runtime.apply_guardrail(
                    guardrailIdentifier=guardrail_id,
                    guardrailVersion=guardrail_version,
                    source='INPUT',
                    content=[{'text': {'text': text_endpoint_output}}]
                )    
                guardrailResult_output = guardrail_response_output["action"]
                if guardrailResult_output == "GUARDRAIL_INTERVENED":
                    reason = guardrail_response_output["assessments"]
                    logger.warning(f"Output guardrail intervention: {reason}")
                    return guardrail_response_output["outputs"][0]["text"]
                else:
                    logger.info("Output passed guardrail check")
                    return text_endpoint_output

            except ClientError as e:
                logger.error(f"AWS API error: {str(e)}")
                raise
    except Exception as e:
        logger.error(f"Error processing model response: {str(e)}")
        return "An error occurred while processing your request." 

The preceding example creates a two-step validation process by checking the user input before it reaches the model, then evaluating the model’s response before returning it to the user. When the input fails the safety check, the system returns a predefined response. Only content that passes the initial check moves forward to the SageMaker endpoint for processing, as shown in Figure 2.

Figure 2: Implementation flow using the ApplyGuardrail API

Figure 2: Implementation flow using the ApplyGuardrail API

This dual-validation approach helps to verify that interactions with your AI application meet your safety standards and comply with your organization’s policies. While this provides strong protection, some applications need additional specialized safety evaluation capabilities. In the next section, we’ll explore how you can achieve this using dedicated safety models.

Using foundation models as external guardrails

Building on the previous safety layers, you can add foundation models designed specifically for content evaluation. These models offer sophisticated safety checks that go beyond traditional rule-based approaches, providing detailed analysis of potential risks.

Foundation models for safety evaluation

Several foundation models are specifically trained for content safety evaluation. For this post, we use Llama Guard as an example. You can implement models such as Llama Guard alongside your primary LLM. Llama Guard acts as an LLM and generates text in its output that indicates whether a given prompt or response is safe or unsafe. If unsafe, it also lists the content categories violated.

Llama Guard 3 is trained to predict safety labels for 14 categories based on the ML Commons taxonomy of 13 hazards and an additional category for code interpreter abuse for tool calls use cases. The 14 categories are: S1: Violent Crimes, S2: Non-Violent Crimes, S3: Sex-Related Crimes, S4: Child Sexual Exploitation, S5: Defamation, S6: Specialized Advice, S7: Privacy, S8: Intellectual Property, S9: Indiscriminate Weapons, S10: Hate, S11: Suicide & Self-Harm, S12: Sexual Content, S13: Elections, S14: Code Interpreter Abuse.

Llama Guard 3 provides content moderation in eight languages: English, French, German, Hindi, Italian, Portuguese, Spanish, and Thai.

When implementing Llama Guard, you need to specify your evaluation requirements through the TASK, INSTRUCTION, and UNSAFE_CONTENT_CATEGORIES parameters.

  • TASK: The type of evaluation to perform
  • INSTRUCTION: Specific guidance for the evaluation
  • UNSAFE_CONTENT_CATEGORIES: Which hazard categories to check

You can use the requirements to specify which hazard categories to monitor based on your use case. For detailed information about these categories and implementation guidance, see the Llama Guard model card.

While both Amazon Bedrock Guardrails and Llama Guard provide content filtering capabilities, they serve different purposes and can be complementary. Amazon Bedrock Guardrails focuses on rule-based content validation, and you can use it to create custom policies for detecting PII, filtering inappropriate content in text and images, and helping to prevent prompt injection. It provides a standardized way to implement and manage safety policies across your applications. Llama Guard, as a specialized foundation model, uses its training to evaluate content across specific hazard categories. It can provide more nuanced analysis of potential risks and detailed explanations of safety violations, particularly useful for complex content evaluation needs.

Implementation options with SageMaker

When implementing external safety models with SageMaker, you have two deployment options:

  • You can deploy separate SageMaker endpoints for each model by using SageMaker JumpStart for quick model deployment or by setting up the model configuration and importing the model from Hugging Face.
  • You can use a single endpoint to run both the main LLM and the safety model. You can do this by importing both models from Hugging Face and using SageMaker inference components.

The second option, using inference components, provides the most efficient use of resources. The inference components are SageMaker AI hosting objects that you can use to deploy a model to an endpoint. In the inference component settings, you specify the model, the endpoint, and how the model uses the resources that the endpoint hosts. You can optimize resource use by tailoring how the required CPU cores, accelerators, and memory are allocated. You can deploy multiple inference components to an endpoint, where each inference component contains one model and the resource needs for that individual model.

After you deploy an inference component, you can directly invoke the associated model when you use the InvokeEndpoint API action. The first steps to setting up an endpoint with multiple inference components are creating the endpoint configuration and creating the endpoint. The following is an example of this:

# create the endpoint configuration

endpoint_name = sagemaker.utils.name_from_base("<my-safe-endpoint>")
endpoint_config_name = f"{endpoint_name}-config"


sm_client.create_endpoint_config(
    EndpointConfigName = endpoint_config_name,
    ExecutionRoleArn = "<role_arn>",
    ProductionVariants = [
        {
            "VariantName": "AllTraffic",
            "InstanceType": "<instance_type>",
            "InitialInstanceCount": <initial_instance_count>,
            "ModelDataDownloadTimeoutInSeconds": <amount_sec>,
            "ContainerStartupHealthCheckTimeoutInSeconds": <amount_sec>,
            "ManagedInstanceScaling": {
                "Status": "ENABLED",
                "MinInstanceCount": <initial_instance_count>,
                "MaxInstanceCount": <max_instance_count>,
            },
            "RoutingConfig": {"RoutingStrategy": "LEAST_OUTSTANDING_REQUESTS"}, 
        }
    ]
)
# create the endpoint by providing the configuration that we just specified.
create_endpoint_response = sm_client.create_endpoint(
    EndpointName = endpoint_name, EndpointConfigName = endpoint_config_name
)

The next step is to create the two inference components. Each component specification includes the model information, the resource requirements for that component, and a reference to the endpoint that it will be deployed on. The following is an example of such components:

# Create Llama Guard component (AWQ quantized version)
create_model_response = sm_client.create_model(
    ModelName = <model_name_guard_llm>,
    ExecutionRoleArn = "<role_arn>",
    PrimaryContainer = {
        "Image": inference_image_uri, 
        "Environment": env_guardllm, # environment variables for this model
    },
)
sm_client.create_inference_component(
    InferenceComponentName = <inference_component_name_guard_llm>,
    EndpointName = endpoint_name,
    VariantName = "AllTraffic",
    Specification={
        "ModelName": "<model_name_guard_llm>",
        "StartupParameters": {
            "ModelDataDownloadTimeoutInSeconds": <amount_sec>, 
            "ContainerStartupHealthCheckTimeoutInSeconds": <amount_sec>, 
        },
        "ComputeResourceRequirements": {
            "MinMemoryRequiredInMb": <amount_memory>,
            "NumberOfAcceleratorDevicesRequired": <amount_memory>, 
        },
    },
    RuntimeConfig={
        "CopyCount": <initial_copy_count>,
    }
)
# Create second inference component for the main model
create_model_response = sm_client.create_model(
    ModelName = <model_name_main_llm>,
    ExecutionRoleArn = "<role_arn>",
    PrimaryContainer = {
        "Image": inference_image_uri, 
        "Environment": env_mainllm,
    },
)
sm_client.create_inference_component(
    InferenceComponentName = <inference_component_name_main_llm>,
    EndpointName = endpoint_name,
    VariantName = variant_name,
    Specification={
        "ModelName": <model_name_guard_llm>,
        "StartupParameters": {
            "ModelDataDownloadTimeoutInSeconds": <amount_sec>, 
            "ContainerStartupHealthCheckTimeoutInSeconds": <amount_sec>, 
        },
        "ComputeResourceRequirements": {
            "MinMemoryRequiredInMb": <amount_memory>, 
            "NumberOfAcceleratorDevicesRequired": <amount_memory>, 
        },
    },
    RuntimeConfig={
        "CopyCount": initial_copy_count,
    },
) 

The complete implementation code and detailed instructions are available in the AWS samples repository.

Safety evaluation workflow

Using SageMaker inference components, you can create an architectural pattern with your safety model as a checkpoint before and after your main model processes requests. The workflow operates as follows:

  1. A user sends a request to your application.
  2. Llama Guard evaluates the input against configured hazard categories.
  3. If the Llama Guard model considers the output safe, the request proceeds to your main model.
  4. The model’s response undergoes another Llama Guard evaluation.
  5. Safe responses are returned to the user. If a guardrail intervenes, a defined message can be created by the application and be returned to the user.

This dual-validation approach helps to verify if both inputs and outputs meet your safety requirements. The workflow is shown in Figure 3:

Figure 3: Dual-validation workflow

Figure 3: Dual-validation workflow

While this architecture provides robust protection, it’s important to understand the characteristics and limitations of the external safety model you choose. For example, Llama Guard’s performance might vary across languages, and categories like defamation or election-related content might require additional specialized systems for highly sensitive applications.

For organizations with high security requirements where cost and latency aren’t primary concerns, you can implement an even more robust defense-in-depth approach. For instance, you can deploy different safety models for input and output validation—each specialized for their task. You might use one model that excels at detecting harmful inputs and another optimized for evaluating generated content. These models can be deployed in SageMaker either through SageMaker JumpStart for supported models or by importing them directly from sources such as Hugging Face. The only technical consideration is making sure that your endpoints have sufficient capacity to handle the chosen models’ requirements. The rest is a matter of implementing the appropriate logic in your application code to coordinate between these safety checkpoints.

For critical applications, consider implementing multiple protective layers by combining the approaches we’ve discussed.

Extending protection with third-party guardrails

While AWS provides comprehensive safety features through built-in safeguards, Amazon Bedrock Guardrails, and support for safety-focused foundation models, some applications require additional specialized protection. Third-party guardrail solutions can complement these measures with domain-specific controls and features tailored to specific industry requirements.

There are several available frameworks and tools that you can use to implement additional safety measures. Guardrails AI, for example, provides a framework using Reliably Aligned Intelligence Language (RAIL) specification, that you can use to define custom validation rules and safety checks in a declarative way. Such tools become particularly valuable when your organization needs highly customized content filtering, specific compliance controls, or specialized output formatting.

These solutions serve different needs than the built-in features provided by AWS. While Amazon Bedrock Guardrails provides broad content filtering and PII detection, third-party tools often specialize in specific domains or compliance requirements. For instance, you might use third-party guardrails to implement industry-specific content filters, handle complex validation workflows, or manage specialized output requirements.

Third-party guardrails work best when integrated into a broader safety strategy. Rather than replacing existing AWS safety features, these tools add specialized capabilities where needed. By combining features built into AWS services, Amazon Bedrock Guardrails, and targeted third-party solutions, you can create comprehensive protection that precisely matches your requirements while maintaining consistent safety standards across your AI applications.

Conclusion

In this post, you’ve seen comprehensive approaches to implementing safety guardrails for AI applications using Amazon SageMaker. Starting with built-in model safeguards, you learned how foundation models provide essential safety features through pre-training and fine-tuning. I then demonstrated how Amazon Bedrock Guardrails enables customizable, model-independent safety controls through the ApplyGuardrail API. Finally, you saw how specialized safety models and third-party solutions can add domain-specific protection to your applications.

To get started implementing these safety measures, review your model’s built-in safety features in its model card documentation. Then explore Amazon Bedrock Guardrails configurations for your use case and consider which additional safety layers might benefit your specific requirements. Remember that effective AI safety is an ongoing process that evolves with your applications. Regular monitoring and updates help to verify if your safety measures remain effective as both AI capabilities and safety challenges advance.

If you have feedback about this post, submit comments in the Comments section below.

Laura Verghote

Laura Verghote

Laura is a Senior Solutions Architect for public sector customers in the EMEA region. She works with customers to design and build solutions in the AWS Cloud, bridging the gap between complex business requirements and technical solutions. She joined AWS as a technical trainer and has wide experience delivering training content to developers, administrators, architects, and partners across EMEA.

AWS Weekly Review: Amazon S3 Express One Zone price cuts, Pixtral Large on Amazon Bedrock, Amazon Nova Sonic, and more (April 14, 2025)

Post Syndicated from Elizabeth Fuentes original https://aws.amazon.com/blogs/aws/aws-weekly-review-amazon-s3-express-one-zone-price-cuts-pixtral-large-on-amazon-bedrock-amazon-nova-sonic-and-more-april-14-2025/

The Amazon Web Services (AWS) Summit 2025 season launched this week, starting with the Paris Summit. These free events bring together the global cloud computing community for learning and collaboration. AWS Community Day Romania, held on April 11th, showcased how the local community creates opportunities for collective growth and inclusion.

Last week’s launches
Announcing up to 85% price reductions for Amazon S3 Express One Zone S3 Express One Zone, a high-performance storage class, now has reduced storage prices by 31 percent, PUT request prices by 55 percent, and GET request prices by 85 percent. In addition, S3 Express One Zone has reduced the per-GB charges for data uploads and retrievals by 60 percent. These charges now apply to all bytes transferred rather than just portions of requests greater than 512 KB.

Here is a price reduction table in the US East (N. Virginia) AWS Region:

Price Previous New Price reduction
Storage
(per GB-Month)
$0.16 $0.11 31%
Writes
(PUT requests)
$0.0025 per 1,000 requests up to 512 KB $0.00113 per 1,000 requests 55%
Reads
(GET requests)
$0.0002 per 1,000 requests up to 512 KB $0.00003 per 1,000 requests 85%
Data upload
(per GB)
$0.008 $0.0032 60%
Data retrievals
(per GB)
$0.0015 $0.0006 60%

AWS announces Pixtral Large 25.02 model in Amazon Bedrock serverless The Pixtral Large 25.02, developed by Mistral AI, combines advanced vision and language understanding, boasting a 128K context window and multilingual capabilities. This agent-centric design simplifies integration with existing systems. Prompt adherence improves reliability when working with Retrieval Augmented Generation (RAG) applications and large context scenarios.

Introducing Amazon Nova Sonic: Human-like voice conversations for generative AI applications Amazon Nova Sonic, the newest addition to the Amazon Nova family of foundation models (FMs) is available in Amazon Bedrock to create human-like voice conversations for applications. It unifies speech and text processing into one model, reducing complexity and enhancing natural interactions. Start today with the Amazon Nova model cookbook repository.

Amazon Bedrock Guardrails enhances generative AI application safety with new capabilitiesAmazon Bedrock Guardrails introduces new capabilities to enhance generative AI application safety, including multimodal toxicity detection, enhanced Personally Identifiable Information (PII) protection, AWS Identity and Access Management (AWS IAM) policy enforcement, selective guardrail application, and monitor mode for pre-deployment analysis.

AWS App Studio introduces a prebuilt solutions catalog and cross-instance Import and Export — This is a prebuilt solutions catalog with ready-to-use applications and patterns and cross-instance Import and Export functionality. These features help you streamline development applications, reducing setup time to under 15 minutes. Learn more about this in AWS App Studio introduces a prebuilt solutions catalog and cross-instance Import and Export blog.

Amazon Nova Reel 1.1: Featuring up to 2-minutes multi-shot videos Amazon Nova Reel 1.1 enhances video generation through Amazon Bedrock with support for 2-minute multi-shot videos. You can now create content using either single prompts for automatic generation or custom prompts for individual shots, offering flexible options for marketing and social media content creation.

AWS IAM Identity Center now offers improved error messages and AWS CloudTrail logging for provisioning issues AWS Identity and Access Management (IAM) Identity Center has enhanced its service with improved error messages and AWS CloudTrail logging capabilities. These updates help users better troubleshoot synchronization issues when managing workforce identities across AWS accounts and applications, while enabling automated monitoring and auditing of provisioning problems.

AWS WAF Console adds new top insights visualizations in additional regionsAWS WAF Console now offers enhanced traffic visualization features in AWS GovCloud (US) Regions. The all traffic dashboard includes new top insights based on Amazon CloudWatch logs, helping customers analyze traffic patterns, identify security threats, and optimize WAF configurations through detailed metrics.

AWS Step Functions expands data source and output options for Distributed MapAWS Step Functions enhances Distributed Map with expanded data source support, including JSONL and various delimited file formats from Amazon Simple Storage Service (Amazon S3). The update also adds new output transformation options, enabling more flexible parallel processing workflows and better integration with downstream systems.

Amazon CloudWatch now provides lock contention diagnostics for Aurora PostgreSQL Amazon CloudWatch Database Insights introduces lock contention diagnostics for Amazon Aurora PostgreSQL in Advanced mode. The feature visualizes blocking and waiting sessions, helping users identify root causes of lock contention issues, with 15-month historical data retention for comprehensive troubleshooting.

Get updated with all the announcements of AWS announcements on the What’s New with AWS? page.

Other AWS blog posts
Reduce ML training costs with Amazon SageMaker HyperPodAmazon SageMaker HyperPod addresses hardware failures in large-scale Machine Learning (ML) model training by automatically detecting and replacing faulty instances. The solution reduces downtime from 280 to 40 minutes per failure, potentially saving 32% of training time for large clusters. For a 10-million GPU-hour training job, this translates to $25.6M in cost savings.

Model customization, RAG, or both: A case study with Amazon Nova — A study comparing model customization with fine-tuning and Retrieval Augmented Generation (RAG) approaches with Amazon Nova models. Key findings show combining both methods yields best results: RAG works well for dynamic data and domain insights, while fine-tuning excels in specialized tasks and latency reduction.

Generate user-personalized communication with Amazon Personalize and Amazon BedrockAmazon Personalize and Amazon Bedrock work together to create personalized marketing emails. Learn how to create personalized user communications by combining Amazon Personalize for movie recommendations with Amazon Bedrock for generating tailored email content based on user preferences and demographics.

Implement human-in-the-loop confirmation with Amazon Bedrock Agents — When implementing human validation in Amazon Bedrock Agents, developers have two primary frameworks at their disposal: user confirmation and return of control (ROC). Using an HR application example, user confirmation allows simple yes/no validation before executing actions, while ROC enables users to modify parameters before execution.

Multi-LLM routing strategies for generative AI applications on AWS — Learn how to implement multi-Large Language Model (LLM) routing strategies for AWS generative AI applications using static routing, dynamic routing with Amazon Bedrock, or custom solutions for optimal model selection and cost efficiency.

Here are my personal favorites posts from community.aws:

Building a RAG System for Video Content Search and Analysis — In this blog, I’ll show you how to build a RAG system that makes video content searchable and analyzable. Unlocking video content has never been more crucial in today’s digital landscape. Whether you’re managing educational materials, corporate training, or entertainment content, the ability to search and analyze video content efficiently can transform how we interact with multimedia resources.

Build Serverless GenAI Apps Faster with Amazon Q Developer CLI AgentAmazon Q Developer CLI Agent enables rapid serverless GenAI app development. With one prompt, it generates infrastructure code, Lambda functions, and integrates with Claude 3 Haiku on Amazon Bedrock.

Speech-to-Speech AI: From Dr. Sbaitso to Amazon Nova Sonic — The evolution of speech-to-speech AI, from Dr. Sbaitso (1990s) to Amazon Nova Sonic. New AWS service enables real-time bidirectional conversations through Amazon Bedrock for more natural applications.

Setup Model Context Protocol (MCP) using Amazon Bedrock — A guide to setting up Model Context Protocol (MCP) desktop client with Amazon Bedrock models, enabling seamless integration between AI applications and external tools using Goose client.

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events:

AWS GenAI LoftsGenAI Lofts available around the world, offer collaborative spaces and immersive experiences for startups and developers. You can join in-person GenAI Loft San Francisco events such as GenAI in EdTech: A Hands-On Workshop (April 15), and Unstructured Data Meetup SF (April 16). Find your nearest event at GenAI Lofts.

AWS Summits — Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Amsterdam (April 16), London (April 30), and Poland (May 5).

AWS re:Inforce — AWS re:Inforce (June 16–18) in Philadelphia, PA, is our annual learning event devoted to all things AWS cloud security. Registration is open. Be ready to join more than 5,000 security builders and leaders.

AWS Community Days — Join community-led conferences featuring technical discussions, workshops, and hands-on labs driven by expert AWS users and industry leaders from around the world. Upcoming AWS Community Days are scheduled for April 19 in Turkey, and on April 29 in Prague with Jeff Barr as Opening Keynote Speaker.

You can browse all upcoming in-person and virtual events.

Create your AWS Builder ID and reserve your alias. Builder ID is a universal login credential that gives you access—beyond the AWS Management Console—to AWS tools and resources, including over 600 free training courses, community features, and developer tools such as Amazon Q Developer.

That’s all for this week. Stay tuned for next week’s Weekly Roundup!

Eli

Thanks to Andra Somesan for the AWS Community Romania photo and Thembile Martis for the AWS Paris Summit photo.

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Streamline data discovery with precise technical identifier search in Amazon SageMaker Unified Studio

Post Syndicated from Ramesh H Singh original https://aws.amazon.com/blogs/big-data/streamline-data-discovery-with-precise-technical-identifier-search-in-amazon-sagemaker-unified-studio/

We’re excited to introduce a new enhancement to the search experience in Amazon SageMaker Catalog, part of the next generation of Amazon SageMaker—exact match search using technical identifiers. With this capability, you can now perform highly targeted searches for assets such as column names, table names, database names, and Amazon Redshift schema names by enclosing search terms in a qualifier such as double quotes (" "). This yields results with exact precision, dramatically improving the speed and accuracy of data discovery.

In this post, we demonstrate how to streamline data discovery with precise technical identifier search in Amazon SageMaker Unified Studio.

Solving real-world discovery challenges

In large, enterprise-scale environments, discovering the right dataset often hinges on pinpointing specific technical identifiers. Users frequently search for exact terms like "customer_id" or "sales_summary_2023" – but conventional keyword and semantic searches often return related results, instead of the exact match.

With the new qualified search capability, entering "customer_id" will surface only those assets whose technical name matches exactly—eliminating noise, saving time, and improving confidence in discovery. Whether you’re a data analyst seeking a specific metric or a data steward validating metadata compliance, this update delivers a more precise, governed, and intuitive search experience.

Built for complex, high-scale catalogs

This feature builds on existing keyword and semantic search capabilities in SageMaker Unified Studio and adds an important layer of control for customers managing complex data catalogs with intricate naming conventions. By reducing time spent filtering partial matches and improving the relevance of results, this enhancement streamlines workflows and helps maintain metadata quality across domains.

One such customer is NatWest, a global banking leader operating across thousands of assets:

“In our complex data ecosystem, discovering the right assets quickly is paramount. In a data-driven banking environment, the new exact and partial match search capabilities in SageMaker Unified Studio have been transformative. By enabling precise discovery of critical attributes like loan IDs and party IDs across thousands of data assets, we’ve dramatically accelerated insight generation while strengthening our metadata governance. This feature cuts through complexity, reduces search time, minimizes errors, and fosters unprecedented collaboration across our data engineering, analytics, and business teams.”

— Manish Mittal, Data Marketplace Engineering Lead, NatWest

Key benefits

With this new capability, SageMaker Catalog users can:

  • Quickly locate precise data assets – Search using known technical names—like "customer_id" or "revenue_code" – to immediately surface the right datasets without sifting through irrelevant results.
  • Reduce false positives and ambiguous matches – Alleviate confusion caused by keyword or semantic searches that return loosely matched results, improving trust in the search experience.
  • Accelerate productivity across data roles – Analysts, stewards, and engineers can find what they need faster—reducing delays in reporting, validation, and development cycles.
  • Strengthen governance and compliance – Surface and validate critical naming conventions and metadata standards (for example, columns prefixed with "pii_" or "audit_" will return all column names starting with pii or audit) to support policy enforcement and audit readiness.

Example use cases

This feature can help the following roles in different use cases:

  • Data analysts – A business analyst preparing a margin analysis report searches for "profit_margin" to locate the exact field across multiple sales datasets. This reduces time-to-insight and makes sure the right metric is used in reporting.
  • Data stewards – A governance lead searches for terms like "audit_log" or "classified_pii" to confirm that all required classifications and logging conventions are in place. This helps enforce data handling policies and validate catalog health.
  • Data engineers – A platform engineer performs a search for "temp_" or "backup_" to identify and clean up unused or legacy assets created during extract, transform, and load (ETL) workflows. This supports data hygiene and infrastructure cost optimization.

Solution demo

To demonstrate the exact match filter solution, we have ingested an individual asset loaded from the TPC-DS tables and also created data product bundling of assets.

The following screenshot shows an example of the data product.

The following screenshot shows an example of the individual assets.

Next, the data analyst wants to search all assets that have customer login details. The customer login is stored as the "c_login" field in the assets.

With the technical identifier feature, the data analyst directly searches the catalog with the identifier "c_login" to get the required results, as shown in the following screenshot.

The data analyst can verify that the login information is present in the returned result.

Conclusion

The addition of precise technical identifier search in SageMaker Unified Studio reinforces a step toward enhancing data discovery and usability in complex data ecosystems. By providing search capabilities based on technical identifiers, this feature addresses the needs of diverse stakeholders, enabling them to efficiently locate the assets they require.

As data continues to grow in scale and complexity, SageMaker Unified Studio remains committed to delivering features that simplify data management, improve productivity, and enable organizations to unlock actionable insights. Start using this enhanced search capability today and experience the difference it brings to your data discovery journey.

Refer to the product documentation to learn more about how to set up metadata rules for subscription and publishing workflows.


About the Authors

Ramesh H Singh is a Senior Product Manager Technical (External Services) at AWS in Seattle, Washington, currently with the Amazon SageMaker team. He is passionate about building high-performance ML/AI and analytics products that enable enterprise customers to achieve their critical goals using cutting-edge technology. Connect with him on LinkedIn.

Pradeep Misra PicPradeep Misra is a Principal Analytics Solutions Architect at AWS. He works across Amazon to architect and design modern distributed analytics and AI/ML platform solutions. He is passionate about solving customer challenges using data, analytics, and AI/ML. Outside of work, Pradeep likes exploring new places, trying new cuisines, and playing board games with his family. He also likes doing science experiments, building LEGOs and watching anime with his daughters.

Rajat Mathur is a Software Development Manager at AWS, leading the Amazon DataZone and SageMaker Unified Studio engineering teams. His team designs, builds, and operates services which make it faster and easier for customers to catalog, discover, share, and govern data. With deep expertise in building distributed data systems at scale, Rajat plays a key role in advancing AWS’s data analytics and AI/ML capabilities.

Jie Lan is a Software Engineer at AWS based in New York, where he works on the Amazon SageMaker team. He is passionate about developing cutting-edge solutions in the big data and AI space, helping customers leverage cloud technology to solve complex problems.

AWS Weekly Roundup: Omdia recognition, Amazon Bedrock RAG evaluation, International Women’s Day events, and more (March 24, 2025)

Post Syndicated from Betty Zheng (郑予彬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-omdia-recognition-amazon-bedrock-rag-evaluation-international-womens-day-events-and-more-march-24-2025/

As we celebrate International Women’s Day (IWD) this March, I had the privilege of attending the ‘Women in Tech’ User Group meetup in Shenzhen last weekend. I was inspired to see over 100 women in tech from different industries come together to discuss AI ethics from a female perspective. Together, we explored strategies such as reducing gender bias in AI systems and promoting diverse representation in model training data. In the AWS Cloud Lab, participants used Amazon Bedrock with large language models (LLMs) to generate rose bloom videos, which was the most popular part of this meetup.

These gatherings are crucial to our efforts to engage more women in AI technology exploration and development, and to help make sure that the generative AI era evolves without gender bias. The collaborative spirit and technical curiosity displayed throughout the event is further proof that diverse teams truly build inclusive and effective solutions.

Speaking of vibrant community engagement, I also had the honor of presenting at Kubernetes Community Day (KCD) Beijing 2025 this weekend. The enthusiasm Omdia Universe: Cloud Container Management & Services 2024-25 reportfor container technologies was remarkable, with nearly 300 developers gathering to share experiences and best practices. During my keynote introducing the DoEKS project from Amazon Web Services (AWS), I was struck by the depth of interest in managed Kubernetes services. The audience’s questions revealed how widely adopted services such as Amazon Elastic Kubernetes Service (Amazon EKS) and Amazon Elastic Container Service (Amazon ECS) have become among Chinese developers building mission-critical applications.This strong community interest aligns perfectly with findings from the Omdia Universe: Cloud Container Management & Services 2024–25 report. In this comprehensive evaluation of container management solutions hosted on public clouds, AWS was recognized as a Leader. The report specifically highlights that AWS offers “widest range of options for working with Kubernetes or its own container management service, across cloud, edge, and on-premises environments.” You can read the full report about AWS offerings to learn more about our comprehensive container portfolio and how we’re helping builders deploy scalable, reliable containerized applications.

Last Week’s launches

In addition to the inspiring community events, here are some AWS launches that caught my attention.

Amazon Q Business browser extension gets upgrades – The Amazon Q Business browser extension now features significant enhancements designed to streamline browser-based tasks. Users gain access to their company’s indexed knowledge alongside web content, direct PDF support within the browser, image file attachment capabilities, and controls to remove irrelevant attachments from conversation context. The expanded context window accommodates larger web pages and more detailed prompts, resulting in more helpful responses. For advanced needs, the extension offers seamless transition to the full Amazon Q Business web experience with access to Actions and Amazon Q Apps. Review the Enhancing web browsing with Amazon Q Business in the documentation for detailed setup instructions and feature descriptions to learn more about this announcement.

Amazon Bedrock RAG evaluation is now generally available – Offering comprehensive assessment of both Bedrock Knowledge Bases and custom Retrieval Augmented Generation (RAG) systems through LLM-as-a-judge methodology. The service evaluates retrieval quality and end-to-end generation with metrics for relevance, correctness, and hallucination detection, and the newly added support for custom RAG pipeline evaluations lets you bring your own input-output pairs and retrieved contexts directly into the evaluation job, along with new citation precision metrics and Amazon Bedrock Guardrails integration for more flexible RAG system optimization. To learn more, visit the Amazon Bedrock Evaluations page and What is Amazon Bedrock? in the documentation.

Amazon Nova expands Tool Choice options for Converse API – We’ve enhanced Amazon Nova with expanded Tool Choice capabilities for the Converse API, giving developers more flexibility in building sophisticated AI applications. This update allows models to determine when to use tools to fulfill user requests more effectively. Learn more in the announcement about expands Tool Choice options.

Amazon Bedrock Guardrails adds policy-based enforcement for responsible AI – Our builders can now enforce responsible AI policies at scale with Amazon Bedrock Guardrails’ new AWS Identity and Access Management (IAM) policy-based enforcement capabilities. This feature helps you to specify required guardrails through IAM policies using the bedrock:GuardrailIdentifiercondition key, so that all model inference calls comply with your organization’s AI safety standards. When your teams make Amazon Bedrock Invoke or Converse API calls, requests are automatically rejected if they don’t include the mandated guardrails, providing consistent protection against undesirable content, sensitive information exposure, and model hallucinations. Refer to the Set up permissions to use Guaidrails for content filtering in the technical documentation and the Amazon Bedrock Guardrails product page to learn more about the announcement about policy based enforcement for responsible AI.

Next generation of Amazon Connect released – We’ve launched the next generation of Amazon Connect, featuring AI-powered interactions designed to strengthen customer relationships and improve business outcomes. This major update brings enhanced agent experiences, smarter customer interactions, and deeper operational insights to contact centers of all sizes. Learn more from the new launch post in the AWS Contact Center Blog.

Amazon Redshift Serverless introduces Current and Trailing release tracksAmazon Redshift Serverless now offers two release tracks to give users more control over their update cadence. The Current track delivers the most up-to-date certified release with the latest features and security updates, while the Trailing track remains on the previous certified release. This dual-track approach allows organizations to validate new releases on select workgroups before implementing them across production environments. Users can easily switch between tracks through the Amazon Redshift console, providing the flexibility to balance innovation with stability for mission-critical workloads. This capability is available in all AWS Regions where Amazon Redshift Serverless is offered. Refer to Tracks for Amazon Redshift provisioned cluster and serverless work groups to learn more about the Current and Trailing tracks in Amazon Redshift Serverless.

AWS WAF now supports URI fragment field matchingAWS WAF has expanded its capability to include URI fragment field matching, allowing security teams to create rules that inspect and match against the fragment portion of URLs. This enhancement enables more precise security controls for web applications that use URI fragments to identify specific sections within pages. Security professionals can now implement more targeted protections, such as restricting access to sensitive page elements, detecting suspicious navigation patterns, and enhancing bot mitigation by analyzing fragment usage patterns characteristic of automated attacks. This feature is available in all AWS Regions where AWS WAF is supported. For more information about URI field for matching, visit the AWS WAF Developer Guide.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS.

Other AWS news

Here are some other additional projects and blog posts that you might find interesting.

Build your generative AI skills at AWS Gen AI Lofts – AWS has established more than 10 global hubs offering training and networking for developers and startups in 2025, where you can gain practical, hands-on experience with the latest AI technologies. These revamped spaces feature dedicated zones where you can participate in workshops on prompt engineering, foundation model (FM) selection, and implementing AI in production environments. If you’re near San Francisco, New York, Tokyo, or other major tech hubs with AWS Gen AI Lofts, stop by to access these free resources and accelerate your generative AI development skills. Check out all of the AWS Gen AI Loft locations and events and to read 5 ways to build your AI skills on AWS Gen AI Loft to learn more.

AWS Lambda‘s architecture for billions of asynchronous invocations – A recent technical article reveals how AWS Lambda handles massive scale through sophisticated engineering approaches. The Lambda asynchronous invocation path employs multiple queuing strategies, consistent hashing for intelligent partitioning, and shuffle-sharding techniques to minimize noisy neighbor effects. The system relies on key observability metrics (AsyncEventReceived, AsyncEventAge, and AsyncEventDropped) to maintain optimal performance. These architectural decisions enable Lambda to process tens of trillions of monthly invocations across 1.5 million active customers while providing reliable scalability and performance isolation. For details read Handling billions of invocations – best practices from AWS Lambda in the AWS computing blog.

AWS is reducing prices by more than 11% for its high-memory U7i instances across all Regions and pricing models. The reduction applies to four instances: u7i-12tb.224xlarge, u7in-16tb.224xlarge, u7in-24tb.224xlarge, and u7in-32tb.224xlarge. The new On-Demand pricing, which covers shared, dedicated, and host tenancy options is retroactive, to March 1, 2025. For new Savings Plan purchases, pricing is effective immediately.

Create your AWS Builder ID and reserve your alias – Builder ID is a universal login credential that gives you access beyond the AWS Management Console to AWS tools and resources, including over 600 free training courses, community features, and developer tools such as Amazon Q Developer.

From community.aws
Here are some of my favorite posts from community.aws.

Model Context Protocol (MCP): why it matters – The recently introduced Model Context Protocol (MCP) creates a standardized way for AI applications to communicate with multiple FMs using consistent prompts and tools.

Build serverless GenAI Apps faster with Amazon Q Developer CLI agent – Discover how Amazon Q Developer CLI Agent revolutionizes cloud development by building a complete serverless generative AI application in minutes instead of days.

Automating code reviews with Amazon Q and GitHub actions – A new developer tutorial demonstrates how to integrate Amazon Q Developer with GitHub Actions to automatically analyze pull requests and provide AI-powered code feedback.

DeepSeek on AWS – A new technical guide demonstrates how to deploy DeepSeek’s powerful open-source AI models on AWS infrastructure. The tutorial provides step-by-step instructions for setting up these cutting-edge models using Amazon SageMaker, Amazon Elastic Compute Cloud (Amazon EC2) instances with GPUs, or through integration with Amazon Bedrock. The guide covers optimization techniques, sample applications, and best practices for balancing performance with cost efficiency.

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events.

Empowering Futures – Women Leading the Way in Tech and Non-Tech Careers – Whether you’re here to expand your professional circle, learn about the AWS Cloud or gain wisdom from inspiring speakers, this event has something for everyone. This is a public event open to everyone in the Seattle area—for free—on March 27, 2025.

AWS at KubeCon + CloudNativeCon London 2025 – Join us at KubeCon London on April 1 – April 4 , at Excel booth S300 for live product demonstrations that help you simplify Kubernetes operations, optimize costs and performance, harness the power of artificial learning and machine learning (AI/ML), and build scalable platform strategies.

That’s all for this week. Check back next Monday for another Weekly Roundup!

Betty

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Connect, share, and query where your data sits using Amazon SageMaker Unified Studio

Post Syndicated from Lakshmi Nair original https://aws.amazon.com/blogs/big-data/connect-share-and-query-where-your-data-sits-using-amazon-sagemaker-unified-studio/

The ability for organizations to quickly analyze data across multiple sources is crucial for maintaining a competitive advantage. Imagine a scenario where the retail analytics team is trying to answer a simple question: Among customers who purchased summer jackets last season, which customers are likely to be interested in the new spring collection?

While the question is straightforward, getting the answer requires piecing together data across multiple data sources such as customer profiles stored in Amazon Simple Storage Service (Amazon S3) from customer relationship management (CRM) systems, historical purchase transactions in an Amazon Redshift data warehouse, and current product catalog information in Amazon DynamoDB. Traditionally, answering this question would involve multiple data exports, complex extract, transform, and load (ETL) processes, and careful data synchronization across systems.

In this blog post, we will demonstrate how business units can use Amazon SageMaker Unified Studio to discover, subscribe to, and analyze these distributed data assets. Through this unified query capability, you can create comprehensive insights into customer transaction patterns and purchase behavior for active products without the traditional barriers of data silos or the need to copy data between systems.

SageMaker Unified Studio provides a unified experience for using data, analytics, and AI capabilities. You can use familiar AWS services for model development, generative AI, data processing, and analytics—all within a single, governed environment. To strike a fine balance of democratizing data and AI access while maintaining strict compliance and regulatory standards, Amazon SageMaker Data and AI Governance is built into SageMaker Unified Studio. With Amazon SageMaker Catalog, teams can collaborate through projects, discover, and access approved data and models using semantic search with generative AI-created metadata, or you can use natural language to ask Amazon Q to find your data. Within SageMaker Unified Studio, organizations can implement a single, centralized permission model with fine-grained access controls, facilitating seamless data and AI asset sharing through streamlined publishing and subscription workflows. Teams can also query the data directly from sources such as Amazon S3 and Amazon Redshift, through Amazon SageMaker Lakehouse.

SageMaker Lakehouse streamlines connecting to, cataloging, and managing permissions on data from multiple sources. Built on AWS Glue Data Catalog and AWS Lake Formation, it organizes data through catalogs that can be accessed through an open, Apache Iceberg REST API to help ensure secure access to data with consistent, fine-grained access controls. SageMaker Lakehouse organizes data access through two types of catalogs: federated catalogs and managed catalogs (shown in the following figure). A catalog is a logical container that organizes objects from a data store, such as schemas, tables, views, or materialized views such as from Amazon Redshift. You can also create nested catalogs to mirror the hierarchical structure of your data sources within SageMaker Lakehouse.

  • Federated catalogs: Through SageMaker Unified Studio, you can create connections to external data sources such as Amazon DynamoDB. See Data connections in Amazon SageMaker Lakehouse for all the supported external data sources. These connections are stored in the AWS Glue Data Catalog (Data Catalog) and registered with Lake Formation, allowing you to create a federated catalog for each available data source.
  • Managed catalogs: A managed catalog refers to the data that resides on Amazon S3 or Redshift Managed Storage (RMS).

The existing Data Catalog becomes the Default catalog (identified by the AWS account number) and is readily available in SageMaker Lakehouse.

If the business units don’t have a data warehouse but need the benefits of one—such as a query result cache and query rewrite optimizations—then, they can create an RMS managed catalog in SageMaker Unified Studio. This is a SageMaker Lakehouse managed catalog backed by RMS storage. The table metadata is managed by Data Catalog. When you create an RMS managed catalog, it deploys an Amazon Redshift managed serverless workgroup. Users can write data to managed RMS tables using Iceberg APIs, Amazon Redshift, or Zero-ETL ingestion from supported data sources.

Functional working model

In SageMaker Unified Studio, the infrastructure team will enable the blueprints and configure the project profiles for tools and technologies to the respective business units to build and monitor their pipelines. They will also onboard the teams to SageMaker Unified Studio, enabling them to build the data products in a single integrated, governed environment. To enforce standardization within the organization, the central governance team can also create hierarchical representations of business units through domain units and dictate certain actions that these teams can perform under a domain unit. Global policies such as data dictionaries (business glossaries), data classification tags, and additional information with metadata forms can be created by the governance team to ensure standardization and consistency within the organization.

Individual business units will use these project profiles based on their needs to process the data using the authorized tool of their choice and create data products. Business units can enjoy the full flexibility to process and consume the data without worrying about the maintenance of the underlying infrastructure. Depending on the nature of the workloads, business units can choose a storage solution that best fits their use case. You can use SageMaker Lakehouse to unify the data across different data sources.

To share the data outside the business unit, the teams will publish the metadata of their data to a SageMaker catalog and make it discoverable and accessible to other business units. Amazon SageMaker Catalog serves as a central repository hub to store both technical and business catalog information of the data product. To establish trust between the data producers and data consumers, SageMaker Catalog also integrates the data quality metrics and data lineage events to track and drive transparency in data pipelines. While sharing the data, data producers of these business units can apply fine grained access control permissions at row and column level to these assets during subscription approval workflows. SageMaker Unified Studio automatically grants subscription access to the subscribed data assets after the subscription request is approved by the data producer. As shown in the following figure, the data sharing capability highlights that the data remains at its origin with the data producer, while consumers from other business units can consume and analyze it using their own compute resources. This approach eliminates any data duplication or data movement.

Solution overview

In this post, we explore two scenarios for sharing data between different teams (retail, marketing, and data analysts). The solution in this post gives you the implementation for a single account use case.

Scenario 1

The retail team needs to create a comprehensive view of customer behavior to optimize their spring collection launch. Their data landscape is diverse:

  • Customer profiles stored in Amazon S3 (default Data Catalog)
  • Historical purchase transactions stored in RMS (SageMaker Lakehouse managed RMS catalog)
  • Inventory information of the product in DynamoDB. (federated catalog)

The team needs to share this unified view with their regional data analysts while maintaining strict data governance protocols. Data analysts discover the data and subscribe to the data. We will also walk through the publishing and subscription workflow as part of the data sharing process. To get a unified view of the customer sales transactions for active products, the data analysts will use Amazon Athena.

Here are the high level steps of the solution implementation as shown in the preceding diagram:

  1. In this post, we take an example of two teams who participate in the collaboration. The retail team has created a project retailsales-sql-project and the data analysts team has created a project dataanalyst-sql-project within SageMaker Unified Studio.
  2. The retail team creates and stores their data in various sources:
    1. customer data in Amazon S3 (contains customer data)
    2. inventory data in a DynamoDB table (contains product catalog information)
    3. store_sales_lakehouse in SageMaker Lakehouse managed RMS (contains purchase history)
  3. The retail team publishes the assets to the project catalog to make them discoverable to other domain members within the organization.
  4. The data analysts team discovers the data and subscribes to the data assets.
  5. An incoming request is sent to the retail team, who then approves the subscription request. After the subscription is approved, data analysts use Athena to create a unified query from all the subscribed data assets to get insights into the data.

In this scenario, we will review how SageMaker Catalog manages the subscription grants to Data Catalog assets (both federated and managed).

For this scenario, we assume that the retail team doesn’t have their own data warehouse and they want to create and manage Amazon Redshift tables using Data Catalog.

Scenario 2

The marketing team needs access to transaction data for campaign optimization. They have campaign performance data stored in an Amazon Redshift data warehouse. However, to have improved campaign ROI and better resource allocation, they need data from the retail team to understand actual customer purchase behavior. To improve the campaign ROI, they need answers to crucial questions such as:

  • What is the true conversion rate across different customer segments?
  • Which customers should be targeted for upcoming promotions?
  • How do seasonal buying patterns affect campaign success?

Here the retail team shares the purchase history data store_sales to the marketing team. In this scenario, shown in the preceding figure, we assume that the retail team has their own data warehouse and uses Amazon Redshift to store the purchase history data.

The high level steps of the solution implementation for this scenario are:

  1. The marketing team has created the project marketing-sql-project within SageMaker Unified Studio.
  2. The retail team has store_sales in Amazon Redshift data warehouse (contains purchase history)
  3. The retail team has published the assets to the project catalog
  4. The marketing team discovers the data and subscribes to the data assets.
  5. An incoming request is sent to the retail team, who then approves the subscription request. After the subscription is approved, the marketing team uses Amazon Redshift to consume the purchase history and identify high-value customer segments.

In this scenario, we will review the process of how SageMaker Catalog grants access to managed Amazon Redshift assets.

Prerequisites

To follow the step by step guide, you must complete the following prerequisites:

Note that the default SQL analytics project profile provides you with a RedshiftServerless blueprint. However, in this post, we want to showcase the data sharing capabilities of different types of SageMaker Lakehouse catalogs (managed and federated).

For the simplicity, we chose the SQL analytics project profile. However, you can also test this by using the Custom project profile by selecting specific blueprints such as LakehouseCatalog and LakeHouseDatabase for scenarios where the business unit doesn’t have their own data warehouse.

Solution walkthrough (Scenario 1)

The first step focuses on preparing the data for each data source for unified access.

Data preparation

In this section, you will create the following data sets:

  • customer data in Amazon S3 (default Data Catalog)
  • inventory data in a DynamoDB table (federated catalog)
  • store_sales_lakehouse in SageMaker Lakehouse managed RMS (managed catalog)
  1. Sign in to SageMaker Unified Studio as a member of the retail team and select the project retailsales-sql-project.
  2. On the top menu, choose Build, and under DATA ANALYSIS & INTEGRATION, select Query Editor.

  1. Select the following options:
    1. Under CONNECTIONS, select Athena (Lakehouse).
    2. Under CATALOGS, select AwsDataCatalog.
    3. Under DATABASES, select glue_db_<environmentid> or the customer glue database name you provided during project creation.
    4. After the options are selected, choose Choose.

When users select a project profile within SageMaker Unified Studio, the system automatically triggers the relevant AWS CloudFormation stack (DataZone-Env-<environmentid>) and deploys the necessary infrastructure resources in the form of environments. Environments are the actual data infrastructure behind a project.

  1. Run the following SQL:
CREATE TABLE customer AS
SELECT 13251813 cust_id,'Joyce Deaton'   cust_name,'Greece'   cust_country, '[email protected]'   cust_email
UNION
SELECT 1581546  ,'Daniel Dow'  ,'India'  , '[email protected]'  
UNION
SELECT 1581536  ,'Marie Lange'  ,'Canada'  , '[email protected]'  
UNION
SELECT 1827661  ,'Wesley Harris'  ,'Rome'  , '[email protected]'  
UNION
SELECT 1581536  ,'Alexander Salyer'  ,'Germany'  , '[email protected]'  
UNION
SELECT 3581536  ,'Jerry Tracy'  ,'Swiss'  , '[email protected]' 
  1. After the SQL is executed, you will find that the customer table has been created in the Lakehouse section under Lakehouse/AwsDataCatalog/glue_db_<environmentid>.

  1. The product catalog is stored in DynamoDB. You can create a new table named inventory in DynamoDB with partition key prod_id through AWS CloudShell with the following command:
aws dynamodb create-table \
    --table-name inventory\
    --attribute-definitions \
AttributeName=prod_id,AttributeType=N \
    --key-schema \
AttributeName=prod_id,KeyType=HASH \
    --provisioned-throughput \
ReadCapacityUnits=5,WriteCapacityUnits=5 \
    --table-class STANDARD
  1. Populate the DynamoDB table using the following commands:
aws dynamodb put-item --table-name inventory --item '{"prod_id": {"N": "1"}, "prod_name": {"S": "Widget A"},"active": {"S": "Y"}}' 

aws dynamodb put-item --table-name inventory --item '{"prod_id": {"N": "2"}, "prod_name": {"S": "Gadget B"},"active": {"S": "Y"}}'

aws dynamodb put-item --table-name inventory --item '{"prod_id": {"N": "3"}, "prod_name": {"S": "Item C"},"active": {"S": "N"}}' 
  1. To use the DynamoDB table in SageMaker Unified Studio, you need to configure a resource-based policy that allows the appropriate actions for the project role.
    1. To create the resource-based policy, navigate to the DynamoDB console and choose Tables from the navigation pane.
    2. Select the Permissions table and choose Create table policy.

  1. The following is an example policy that allows connecting to DynamoDB tables as a federated source. Replace the <aws_region> with the Region you are working on, <aws_account_id> with the AWS Account ID where DynamoDB is deployed, <dynamodb_table> with the DynamoDB table (in this case inventory) that you intend to query from Amazon SageMaker Unified Studio and <datazone_usr_role_xxxxxxxxxxxxxx_yyyyyyyyyyyyyy> with the Project role Amazon Resource Name (ARN) in SageMaker Unified Studio portal. You can get the project role ARN by navigating to the project in SageMaker Unified Studio and then to Project overview.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Principal": "*",
            "Action": [
                "dynamodb:Query",
                "dynamodb:Scan",
                "dynamodb:DescribeTable",
                "dynamodb:PartiQLSelect",
                "dynamodb:BatchWriteItem"
            ],
            "Resource": "arn:aws:dynamodb:<aws_region>:<aws_accountid>:table/<dynamodb_table>",
            "Condition": {
                "ArnEquals": {
                    "aws:PrincipalArn": "arn:aws:iam::<aws_accountid>:role/<datazone_usr_role_xxxxxxxxxxxxxx_yyyyyyyyyyyyyy>"
                }
            }
        }
    ]
}

After the policies are incorporated on the DynamoDB table, create an SageMaker Lakehouse connection within SageMaker Unified Studio. As shown in the example, dynamodb-connection-catalogs is created.

  1. After the connection is successfully established, you will see the DynamoDB table inventory under Lakehouse.

The next step is to create a managed catalog for RMS objects using SageMaker Lakehouse.

  1. Choose Data in the navigation pane.
  2. In the data explorer, choose the plus icon to add a data source.
  3. Select Create Lakehouse catalog.
  4. Choose Next.

  1. Enter the name of the catalog. The catalog name provided in the example is redshift-lakehouse-connection-catalogs. Choose Add data.

  1. After the connection is created, you will see the catalog under Lakehouse.

  1. This creates a managed Amazon Redshift Serverless workgroup in your AWS account. You will see a new database dev@<redshift-catalog-name> in the managed Amazon Redshift Serverless workgroup.
    1. On the top menu, choose Build, and under DATA ANALYSIS & INTEGRATION, select Query Editor.
    2. Select Redshift (Lakehouse) from CONNECTIONSdev@<redshift-catalog-name> from DATABASES and public from SCHEMAS

  1. Run the following SQL in order. The SQL creates the store_sales_lakehouse table in the dev database in the public schema. The retail team inserts data into the store_sales_lakehouse table.
CREATE TABLE public.store_sales_lakehouse (
    sale_id INTEGER IDENTITY(1,1) PRIMARY KEY,
    cust_id INTEGER NOT NULL,
    sale_date DATE NOT NULL,
    sale_amount DECIMAL(10, 2) NOT NULL,
    prod_id INTEGER  NOT NULL,
    last_purchase_date DATE
);
INSERT INTO public.store_sales_lakehouse (cust_id, sale_date, sale_amount, prod_id, last_purchase_date)
VALUES
(13251813, '2023-01-15', 150.00, 1, '2023-01-15'),
(29033279, '2023-01-20', 200.00, 4, '2023-01-20'),
(12755125, '2023-02-01', 75.50, 3, '2023-02-01'),
(26009249, '2023-02-10', 300.00, 2, '2023-02-10'),
(3270685, '2023-02-15', 125.00, 2, '2023-02-15'),
(6520539, '2023-03-01', 100.00, 2, '2023-03-01'),
(10251183, '2023-03-10', 250.00, 1, '2023-03-10'),
(10251283, '2023-03-15', 180.00, 1, '2023-03-15'),
(10251383, '2023-04-01', 90.00, 2, '2023-04-01'),
(10251483, '2023-04-10', 220.00, 3, '2023-04-10'),
(10251583, '2023-04-15', 175.00, 3, '2023-04-15'),
(10251683, '2023-05-01', 130.00, 1, '2023-05-01'),
(10251783, '2023-05-10', 280.00, 1, '2023-05-10'),
(10251883, '2023-05-15', 195.00, 4, '2023-05-15'),
(10251983, '2023-06-01', 110.00, 2, '2023-06-01'),
(10251083, '2023-06-10', 270.00, 1, '2023-06-10'),
(10252783, '2023-06-15', 185.00, 2, '2023-06-15'),
(10253783, '2023-07-01', 95.00, 3, '2023-07-01'),
(10254783, '2023-07-10', 240.00, 1, '2023-07-10'),
(10255783, '2023-07-15', 160.00, 3, '2023-07-15');
  1. On successful creation of the table, you should now be able to query the data. Select the table store_sales_lakehouse and select Query with Redshift.

Import assets to the project catalog from various data sources

To share your assets outside your own project to other business units, you must first bring your metadata to SageMaker Catalog. To import the assets into the project’s inventory, you need to create a data source in the project catalog. In this section, we show you how to import the technical metadata from AWS Glue data catalogs. Here, you will import data assets from various sources that you have created as part of your data preparation.

  1. Sign in to SageMaker Unified Studio as a member of the retail team. Select the project retailsales-sql-project, under Project catalog. Choose Data sources and import the assets by choosing Run.

  1. To import the federated catalog, create a new data source and choose Run. This will import the metadata of the inventory data from DynamoDB table.

  1. After successful run of all the data sources, choose Assets under Project catalog in the navigation plane. You will find all the assets in the Inventory of Project catalog.

Publish the assets

To make the assets discoverable to the data analysts team, the retail team must publish their assets.

  1. In the project retailsales-sql-project, choose Project catalog and select Assets.
  2. Select each asset in the INVENTORY tab, enrich the asset with the automated metadata generation and PUBLISH ASSET.

Discover the assets

SageMaker Catalog within SageMaker Unified Studio enables efficient data asset discovery and access management. The data analysts team signs in to SageMaker Unified Studio and selects the project dataanalyst-sql-project. The data analysts team then locates the desired assets in SageMaker Catalog and initiates the subscription request.

In this section, members of dataanalyst-sql-project browse the catalog and find the assets. There are multiple ways to find the desired assets.

  • Sign in to SageMaker Unified Studio as a member of the data analysts team. Choose Discover in the top navigation bar and select Catalog. Find the desired asset by browsing or entering the name of the asset into the search bar.
  • Search for the asset through a conversational interface using Amazon Q.
  • Use the faceted filter search by selecting the desired project in the BROWSE CATALOG.

The data analysts team selects the project retailsales-sql-project.

Subscribe to the assets

The data analysts team submits a subscription request with an appropriate justification for each of these assets.

  1. For each asset, choose SUBSCRIBE.
  2. Select dataanalyst-sql-project in Project.
  3. Provide the Reason for request as “need this data for analysis”.

Note that during the subscription process, the requester sees a message that the asset access control and fulfillment will be Managed. This means that SageMaker Unified Studio automatically manages subscription access grants and permissions for these assets.

Subscription approval workflow

To approve the subscription request, you must be a member of the retail team and select the project that has published the asset.

  1. Sign in to SageMaker Unified Studio as a member of the retail team and select the project retailsales-sql-project.
  2. In the navigation pane, choose Project catalog and then select Subscription requests.
  3. In INCOMING REQUESTS, choose the REQUESTED tab and select View request for each asset to see detailed information of the subscription request.

  • REQUEST DETAILS provides information about the subscribing project, the requestor, and the justification to access the asset.
  • RESPONSE DETAILS provides an option to approve the subscription with full access to the data (Full access) or restricted access to the data (Approve with row or column filters). With restricted access to data, the subscription approval workflow process offers granular access control for sensitive data through row-level filtering and column-level filtering. Using row filters, approvers can restrict access to specific records based on defined criteria. Using column filters, approvers can control access to specific columns within the data sets. This allows excluding sensitive fields while sharing the relevant data. Approvers can implement these filters during the approval process, helping to ensure that the data access aligns with the organization’s security requirements and compliance policies. For this post, select Full access in the RESPONSE DETAILS
  • (Optional) Decision comment is where you can add a comment about accepting or rejecting the subscription request.
  • Choose APPROVE.

  1. Repeat the subscription approval workflow process for all the requested assets.
  2. After all the subscription requests are approved, choose the APPROVED tab to view all the approved assets.

Subscription fulfillment methods

After subscription approval, a fulfillment process manages access to the assets. SageMaker Unified Studio provides fulfillment methods for managed assets and unmanaged assets.

  • Managed assets: SageMaker Unified Studio automatically manages the fulfillment and permissions for assets such as AWS Glue tables and Amazon Redshift tables and views.
  • Unmanaged assets: For unmanaged assets, permissions are handled externally. SageMaker Unified Studio publishes standard events for actions such as approvals through Amazon EventBridge, enabling integration with other AWS services or third-party solutions for custom integrations.

In this scenario 1, because the assets are Data Catalogs, SageMaker Unified Studio grants and manages access to these managed assets on your behalf through Lake Formation. See the SageMaker Unified Studio subscription workflow for updates on sharing options.

Analyze the data

The data analysts team uses the subscribed data assets from varied sources to get unified insights.

  1. As a data analyst, sign in to SageMaker Unified Studio and select the project dataanalyst-sql-project. In the navigation pane, choose Project catalog and select Assets.
  2. Choose the SUBSCRIBED tab to find all the subscribed assets from the retailsales-sql-project.
  3. The status under each asset is Asset accessible. This indicates that the subscription grants are fulfilled and the data analysts team can now consume the assets with the compute of their choice.

Query using Athena (subscription grants fulfilled using Lake Formation)

As a member of the data analysts team, create a unified view to get purchase history with customer information for active products.

  1. In the dataanalyst-sql-project project, go to Build and select Query Editor.
  2. Use the following sample query to get the required information. Replace glue_db_<environmentid> with your subscribed glue database.
select * from "redshift-lakehouse-connection-catalogs/dev"."public"."store_sales_lakehouse" sales 
 left  join "awsdatacatalog"."glue_db_<environmentid>"."customer" customer
 on sales.cust_id=customer.cust_id
 inner  join "dynamodb-connection-catalogs"."default"."inventory" inventory
 on sales.prod_id = inventory.prod_id
 where inventory.active ='Y'

Solution walk-through (Scenario 2)

In this scenario, we assume that the retail team stores the purchase history data in their Amazon Redshift data warehouse. Because you’re using the default SQL analytics project profile to create the project, you will use a Redshift Serverless compute (project.redshift). The purchase history data is shared with the marketing team for enhanced campaign performance.

  1. Sign in to SageMaker Unified Studio as a member of the retail team and select the project retailsales-sql-project.
  2. On the top menu, choose Build, and under DATA ANALYSIS & INTEGRATION, select Query Editor
  3. Select the following options:
    • Under CONNECTIONS, select Redshift(Lakehouse).
    • Under CATALOGS, select dev.
    • Under DATABASES, select public.
  4. Run the following SQL:
CREATE TABLE public.store_sales (
sale_id INTEGER IDENTITY(1,1) PRIMARY KEY,
cust_id INTEGER NOT NULL,
sale_date DATE NOT NULL,
sale_amount DECIMAL(10, 2) NOT NULL,
prod_id INTEGER  NOT NULL,
last_purchase_date DATE
);
INSERT INTO public.store_sales (cust_id, sale_date, sale_amount, prod_id, last_purchase_date)
VALUES
(13251813, '2023-01-15', 150.00, 1, '2023-01-15'),
(29033279, '2023-01-20', 200.00, 4, '2023-01-20'),
(12755125, '2023-02-01', 75.50, 3, '2023-02-01'),
(26009249, '2023-02-10', 300.00, 2, '2023-02-10'),
(3270685, '2023-02-15', 125.00, 2, '2023-02-15'),
(6520539, '2023-03-01', 100.00, 2, '2023-03-01'),
(10251183, '2023-03-10', 250.00, 1, '2023-03-10'),
(10251283, '2023-03-15', 180.00, 1, '2023-03-15'),
(10251383, '2023-04-01', 90.00, 2, '2023-04-01'),
(10251483, '2023-04-10', 220.00, 3, '2023-04-10'),
(10251583, '2023-04-15', 175.00, 3, '2023-04-15'),
(10251683, '2023-05-01', 130.00, 1, '2023-05-01'),
(10251783, '2023-05-10', 280.00, 1, '2023-05-10'),
(10251883, '2023-05-15', 195.00, 4, '2023-05-15'),
(10251983, '2023-06-01', 110.00, 2, '2023-06-01'),
(10251083, '2023-06-10', 270.00, 1, '2023-06-10'),
(10252783, '2023-06-15', 185.00, 2, '2023-06-15'),
(10253783, '2023-07-01', 95.00, 3, '2023-07-01'),
(10254783, '2023-07-10', 240.00, 1, '2023-07-10'),
(10255783, '2023-07-15', 160.00, 3, '2023-07-15');

5. On successful execution of the query, you will see store_sales under Redshift in the navigation pane.

Import the asset to the project catalog inventory

To share your assets outside your own project to other marketing business units, you must first share your metadata to SageMaker Catalog. To import the assets into the project’s inventory, you need to run the data source in the project catalog.

In the project retailsales-sql-project, under Project catalog, select Data sources and import the asset store-sales. Select the highlighted data source and choose Run as shown in the screenshot.

Publish the asset

To make the assets discoverable to the marketing team, the retail team must publish their asset.

  1. Go to the navigation pane and choose Project catalog, and then select Assets.
  2. Select store-sales in the INVENTORY tab, enrich the asset with the automated metadata generation and PUBLISH ASSET as illustrated in the screenshot.

Discover and subscribe the asset

The marketing team discovers and subscribes to the store-sales asset.

  1. Sign in to SageMaker Unified Studio as a member of the marketing team and select marketing-sql-project.
  2. Navigate to the Discover menu in the top navigation bar and choose Catalog. Find the desired asset by browsing or entering the name of the asset into the search bar.
  3. Select the asset and choose SUBSCRIBE.
  4. Enter a justification in Reason for request and choose REQUEST.

Subscription approval workflow

The retail team gets an incoming request in their project to approve the subscription request.

  1. Sign in to the SageMaker Unified Studio and select the project retailsales-sql-project as a member of the retail team. Under Project catalog, select Subscription requests.
  2. In the INCOMING REQUESTS, under the REQUESTED tab, select View request for store-sales.

  1. You will see detailed information for the subscription request.
  2. Select Full access in the RESPONSE DETAILS and choose APPROVE.

Analyze the data

Sign in to SageMaker Unified Studio as a member of the marketing team and select marketing-sql-project.

  1. In the Project catalog, select Assets and choose the SUBSCRIBED tab to find all the subscribed assets from the retailsales-sql-project.
  2. Notice the status under the asset marked as Asset accessible. This indicates that the subscription grants are fulfilled and the marketing team can now consume the asset with the compute of their choice.

Query using Amazon Redshift (subscription grants fulfilled using native Amazon Redshift data sharing)

To query the shared data with Amazon Redshift compute, select Build and then Query Editor. Select the following options

  1. Under CONNECTIONS, select Redshift(Lakehouse).
  2. Under CATALOGS, select dev.
  3. Under DATABASES, select project.
select * from "dev"."project"."store_sales" sales  

When a subscription to an Amazon Redshift table or view is approved, SageMaker Unified Studio automatically adds the subscribed asset to the consumer’s Amazon Redshift Serverless workgroup for the project. Notice the subscribed asset is shared under the folder project. In the Redshift navigation pane, you can also see the datashare created between the source and the target cluster. In this case, because the data is shared in the same account but between different clusters, SageMaker Unified Studio creates a view in the target database and permissions are granted on the view. See Grant access to managed Amazon Redshift assets in Amazon SageMaker Unified Studio for information about data sharing options within Amazon Redshift.

Clean up

Make sure you remove the SageMaker Unified Studio resources to avoid any unexpected costs. Start by deleting the connections, catalogs, underlying data sources, projects, databases, and domain that you created for this post. For additional details, see the Amazon SageMaker Unified Studio Administrator Guide.

Conclusion

In this post, we explored two distinct approaches to data sharing and analytics.

Business units without an existing data warehouse can use a SageMaker Lakehouse managed RMS catalog. In the first scenario, we showcased subscription fulfillment of AWS Glue Data Catalogs using AWS Lake Formation for federated and managed catalogs. The data analysts team was able to connect and subscribe to the data shared by the retail team that resided in Amazon S3, Amazon Redshift, and other data sources such as DynamoDB through SageMaker Lakehouse.

In the second scenario, we demonstrated the native data-sharing capabilities of Amazon Redshift. In this scenario, we assume that the retail team has sales transactions stored in an Amazon Redshift data warehouse. Using the data sharing feature of Amazon Redshift, the asset was shared to the marketing team using Amazon SageMaker Unified Studio.

Both approaches enable unified querying across varied data sources with teams able to efficiently discover, publish, and subscribe to data assets while maintaining strict access controls through Amazon SageMaker Data and AI Governance. Subscription fulfillment is automated, reducing the administrative overhead. Using the query-in-place approach eliminates data redundancy and maintains data consistency while allowing unified analysis across data sources through a single integrated experience.

To learn more, see the Amazon SageMaker Unified Studio Administrator Guide and the following resources:


About the authors

Lakshmi Nair is a Senior Analytics Specialist Solutions Architect at AWS. She specializes in designing advanced analytics systems across industries. She focuses on crafting cloud-based data platforms, enabling real-time streaming, big data processing, and robust data governance. She can be reached through LinkedIn

Ramkumar Nottath is a Principal Solutions Architect at AWS focusing on Analytics services. He enjoys working with various customers to help them build scalable, reliable big data and analytics solutions. His interests extend to various technologies such as analytics, data warehousing, streaming, data governance, and machine learning. He loves spending time with his family and friends. 
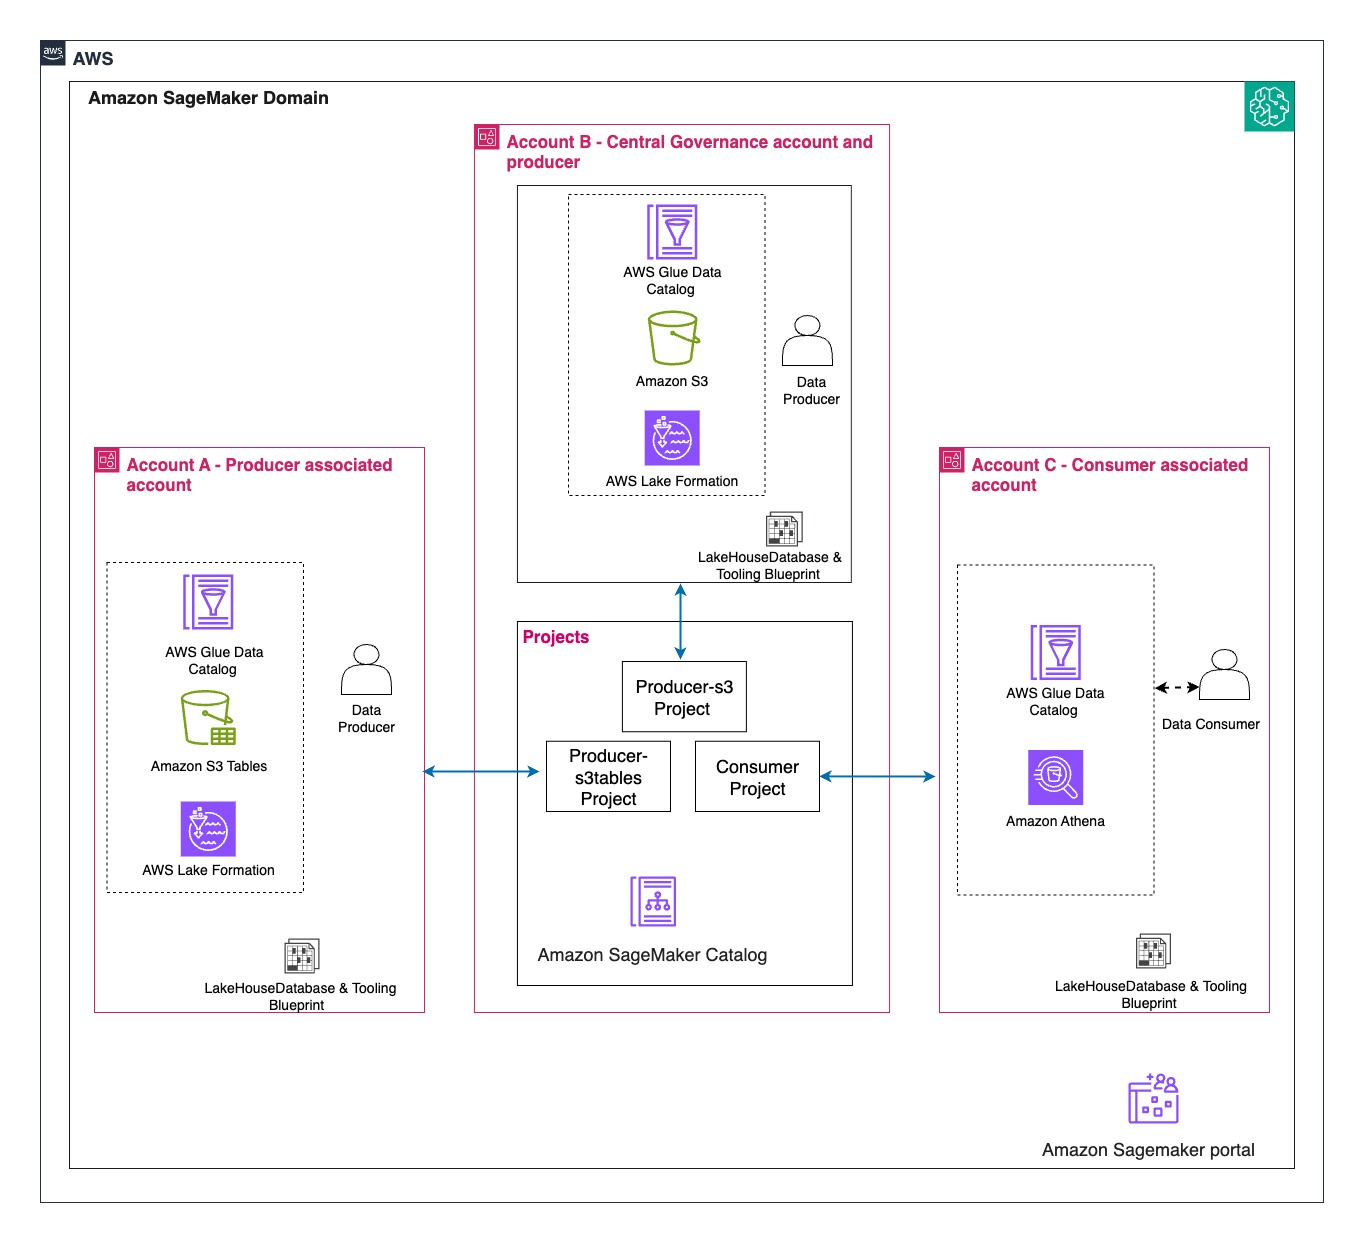
AWS Pi Day 2025: Data foundation for analytics and AI

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-pi-day-data-foundation-for-analytics-and-ai/

Every year on March 14 (3.14), AWS Pi Day highlights AWS innovations that help you manage and work with your data. What started in 2021 as a way to commemorate the fifteenth launch anniversary of Amazon Simple Storage Service (Amazon S3) has now grown into an event that highlights how cloud technologies are transforming data management, analytics, and AI.

This year, AWS Pi Day returns with a focus on accelerating analytics and AI innovation with a unified data foundation on AWS. The data landscape is undergoing a profound transformation as AI emerges in most enterprise strategies, with analytics and AI workloads increasingly converging around a lot of the same data and workflows. You need an easy way to access all your data and use all your preferred analytics and AI tools in a single integrated experience. This AWS Pi Day, we’re introducing a slate of new capabilities that help you build unified and integrated data experiences.

The next generation of Amazon SageMaker: The center of all your data, analytics, and AI
At re:Invent 2024, we introduced the next generation of Amazon SageMaker, the center of all your data, analytics, and AI. SageMaker includes virtually all the components you need for data exploration, preparation and integration, big data processing, fast SQL analytics, machine learning (ML) model development and training, and generative AI application development. With this new generation of Amazon SageMaker, SageMaker Lakehouse provides you with unified access to your data and SageMaker Catalog helps you to meet your governance and security requirements. You can read the launch blog post written by my colleague Antje to learn more details.

Core to the next generation of Amazon SageMaker is SageMaker Unified Studio, a single data and AI development environment where you can use all your data and tools for analytics and AI. SageMaker Unified Studio is now generally available.

SageMaker Unified Studio facilitates collaboration among data scientists, analysts, engineers, and developers as they work on data, analytics, AI workflows, and applications. It provides familiar tools from AWS analytics and artificial intelligence and machine learning (AI/ML) services, including data processing, SQL analytics, ML model development, and generative AI application development, into a single user experience.

SageMaker Unified Studio

SageMaker Unified Studio also brings selected capabilities from Amazon Bedrock into SageMaker. You can now rapidly prototype, customize, and share generative AI applications using foundation models (FMs) and advanced features such as Amazon Bedrock Knowledge BasesAmazon Bedrock Guardrails, Amazon Bedrock Agents, and Amazon Bedrock Flows to create tailored solutions aligned with your requirements and responsible AI guidelines all within SageMaker.

Last but not least, Amazon Q Developer is now generally available in SageMaker Unified Studio. Amazon Q Developer provides generative AI powered assistance for data and AI development. It helps you with tasks like writing SQL queries, building extract, transform, and load (ETL) jobs, and troubleshooting, and is available in the Free tier and Pro tier for existing subscribers.

You can learn more about SageMaker Unified Studio in this recent blog post written by my colleague Donnie.

During re:Invent 2024, we also launched Amazon SageMaker Lakehouse as part of the next generation of SageMaker. SageMaker Lakehouse unifies all your data across Amazon S3 data lakes, Amazon Redshift data warehouses, and third-party and federated data sources. It helps you build powerful analytics and AI/ML applications on a single copy of your data. SageMaker Lakehouse gives you the flexibility to access and query your data in-place with Apache Iceberg–compatible tools and engines. In addition, zero-ETL integrations automate the process of bringing data into SageMaker Lakehouse from AWS data sources such as Amazon Aurora or Amazon DynamoDB and from applications such as Salesforce, Facebook Ads, Instagram Ads, ServiceNow, SAP, Zendesk, and Zoho CRM. The full list of integrations is available in the SageMaker Lakehouse FAQ.

Building a data foundation with Amazon S3
Building a data foundation is the cornerstone of accelerating analytics and AI workloads, enabling organizations to seamlessly manage, discover, and utilize their data assets at any scale. Amazon S3 is the world’s best place to build a data lake, with virtually unlimited scale, and it provides the essential foundation for this transformation.

I’m always astonished to learn about the scale at which we operate Amazon S3: It currently holds over 400 trillion objects, exabytes of data, and processes a mind-blowing 150 million requests per second. Just a decade ago, not even 100 customers were storing more than a petabyte (PB) of data on S3. Today, thousands of customers have surpassed the 1 PB milestone.

Amazon S3 stores exabytes of tabular data, and it averages over 15 million requests to tabular data per second. To help you reduce the undifferentiated heavy lifting when managing your tabular data in S3 buckets, we announced Amazon S3 Tables at AWS re:Invent 2024. S3 Tables are the first cloud object store with built-in support for Apache Iceberg. S3 tables are specifically optimized for analytics workloads, resulting in up to threefold faster query throughput and up to tenfold higher transactions per second compared to self-managed tables.

Today, we’re announcing the general availability of Amazon S3 Tables integration with Amazon SageMaker Lakehouse  Amazon S3 Tables now integrate with Amazon SageMaker Lakehouse, making it easy for you to access S3 Tables from AWS analytics services such as Amazon Redshift, Amazon Athena, Amazon EMR, AWS Glue, and Apache Iceberg–compatible engines such as Apache Spark or PyIceberg. SageMaker Lakehouse enables centralized management of fine-grained data access permissions for S3 Tables and other sources and consistently applies them across all engines.

For those of you who use a third-party catalog, have a custom catalog implementation, or only need basic read and write access to tabular data in a single table bucket, we’ve added new APIs that are compatible with the Iceberg REST Catalog standard. This enables any Iceberg-compatible application to seamlessly create, update, list, and delete tables in an S3 table bucket. For unified data management across all of your tabular data, data governance, and fine-grained access controls, you can also use S3 Tables with SageMaker Lakehouse.

To help you access S3 Tables, we’ve launched updates in the AWS Management Console. You can now create a table, populate it with data, and query it directly from the S3 console using Amazon Athena, making it easier to get started and analyze data in S3 table buckets.

The following screenshot shows how to access Athena directly from the S3 console.

S3 console : create table with AthenaWhen I select Query tables with Athena or Create table with Athena, it opens the Athena console on the correct data source, catalog, and database.

S3 Tables in Athena

Since re:Invent 2024, we’ve continued to add new capabilities to S3 Tables at a rapid pace. For example, we added schema definition support to the CreateTable API and you can now create up to 10,000 tables in an S3 table bucket. We also launched S3 Tables into eight additional AWS Regions, with the most recent being Asia Pacific (Seoul, Singapore, Sydney) on March 4, with more to come. You can refer to the S3 Tables AWS Regions page of the documentation to get the list of the eleven Regions where S3 Tables are available today.

Amazon S3 Metadataannounced during re:Invent 2024— has been generally available since January 27. It’s the fastest and easiest way to help you discover and understand your S3 data with automated, effortlessly-queried metadata that updates in near real time. S3 Metadata works with S3 object tags. Tags help you logically group data for a variety of reasons, such as to apply IAM policies to provide fine-grained access, specify tag-based filters to manage object lifecycle rules, and selectively replicate data to another Region. In Regions where S3 Metadata is available, you can capture and query custom metadata that is stored as object tags. To reduce the cost associated with object tags when using S3 Metadata, Amazon S3 reduced pricing for S3 object tagging by 35 percent in all Regions, making it cheaper to use custom metadata.

AWS Pi Day 2025
Over the years, AWS Pi Day has showcased major milestones in cloud storage and data analytics. This year, the AWS Pi Day virtual event will feature a range of topics designed for developers and technical decision-makers, data engineers, AI/ML practitioners, and IT leaders. Key highlights include deep dives, live demos, and expert sessions on all the services and capabilities I discussed in this post.

By attending this event, you’ll learn how you can accelerate your analytics and AI innovation. You’ll learn how you can use S3 Tables with native Apache Iceberg support and S3 Metadata to build scalable data lakes that serve both traditional analytics and emerging AI/ML workloads. You’ll also discover the next generation of Amazon SageMaker, the center for all your data, analytics, and AI, to help your teams collaborate and build faster from a unified studio, using familiar AWS tools with access to all your data whether it’s stored in data lakes, data warehouses, or third-party or federated data sources.

For those looking to stay ahead of the latest cloud trends, AWS Pi Day 2025 is an event you can’t miss. Whether you’re building data lakehouses, training AI models, building generative AI applications, or optimizing analytics workloads, the insights shared will help you maximize the value of your data.

Tune in today and explore the latest in cloud data innovation. Don’t miss the opportunity to engage with AWS experts, partners, and customers shaping the future of data, analytics, and AI.

If you missed the virtual event on March 14, you can visit the event page at any time—we will keep all the content available on-demand there!

— seb


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Accelerate analytics and AI innovation with the next generation of Amazon SageMaker

Post Syndicated from G2 Krishnamoorthy original https://aws.amazon.com/blogs/big-data/accelerate-analytics-and-ai-innovation-with-the-next-generation-of-amazon-sagemaker/

At AWS re:Invent 2024, we announced the next generation of Amazon SageMaker, the center for all your data, analytics, and AI. Amazon SageMaker brings together widely adopted AWS machine learning (ML) and analytics capabilities and addresses the challenges of harnessing organizational data for analytics and AI through unified access to tools and data with governance built in. It enables teams to securely find, prepare, and collaborate on data assets and build analytics and AI applications through a single experience, accelerating the path from data to value.

At the core of the next generation of Amazon SageMaker is Amazon SageMaker Unified Studio, a single data and AI development environment where you can find and access your organization’s data and act on it using the best tool for the job across virtually any use case. We are excited to announce the general availability of SageMaker Unified Studio.

In this post, we explore the benefits of SageMaker Unified Studio and how to get started.

Benefits of SageMaker Unified Studio

SageMaker Unified Studio brings together the functionality and tools from existing AWS Analytics and AI/ML services, including Amazon EMR, AWS Glue, Amazon Athena, Amazon Redshift, Amazon Bedrock, and Amazon SageMaker AI. From within the unified studio, you can discover data and AI assets from across your organization, then work together in projects to securely build and share analytics and AI artifacts, including data, models, and generative AI applications. Governance features including fine-grained access control are built into SageMaker Unified Studio using Amazon SageMaker Catalog to help you meet enterprise security requirements across your entire data estate.

Unified access to your data is provided by Amazon SageMaker Lakehouse, a unified, open, and secure data lakehouse built on Apache Iceberg open standards. Whether your data is stored in Amazon Simple Storage Service (Amazon S3) data lakes, Redshift data warehouses, or third-party and federated data sources, you can access it from one place and use it with Iceberg-compatible engines and tools. In addition, SageMaker Lakehouse now integrates with Amazon S3 Tables, the first cloud object store with native Apache Iceberg support, so you can use SageMaker Lakehouse to create, query, and process S3 Tables efficiently using various analytics engines in SageMaker Unified Studio as well as Iceberg-compatible engines like Apache Spark and PyIceberg.

Capabilities from Amazon Bedrock are now generally available in SageMaker Unified Studio, allowing you to rapidly prototype, customize, and share generative AI applications in a governed environment. Users have an intuitive interface to access high-performing foundation models (FMs) in Amazon Bedrock, including the Amazon Nova model series, and the ability to create Agents, Flows, Knowledge Bases, and Guardrails with a few clicks.

Amazon Q Developer, the most capable generative AI assistant for software development, can be used within SageMaker Unified Studio to streamline tasks across the data and AI development lifecycle, including code authoring, SQL generation, data discovery, and troubleshooting.

A new integrated way of working

The general availability of SageMaker Unified Studio represents another meaningful step in our journey to offer our customers a streamlined way to work with their data, whether for analytics or AI. Many of our customers have told us that you are building data-driven applications to guide business decisions, improve agility, and drive innovation, but that these applications are complex to build because they require collaboration across teams and the integration of data and tools. Not only is it time consuming for users to learn multiple development experiences, but because data, code, and other development artifacts are stored separately, it is challenging for users to understand how they interact with each other and to use them cohesively. Configuring and governing access is also a cumbersome manual process. To overcome these hurdles, many organizations are building bespoke integrations between services, tools, and homegrown access management systems. However, what you need is the flexibility to adopt the best services for your use case while empowering your data teams with a unified development experience.

“When we build data-driven applications for our customers, we want a unified platform where the technologies work together in an integrated way. Amazon SageMaker Unified Studio streamlines our solution delivery processes through comprehensive analytics capabilities, a unified studio experience, and a lakehouse that integrates data management across data warehouses and data lakes. Amazon SageMaker Unified Studio reduces the time-to-value for our customers’ data projects by up to 40%, helping us with our mission to accelerate our customers’ digital transformation journey.”

—Akihiro Suzue, Head of Solutions Sector, NTT DATA; Yuji Shono, Senior Manager, Apps & Data Technology Department, NTT DATA; Yuki Saito, Manager, Digital Success Solutions Division, NTT DATA

Millions of organizations trust AWS and utilize our comprehensive set of purpose-built analytics, AI/ML, and generative AI capabilities to power data-driven applications without compromising on performance, scale, or cost. Our goal for the next generation of Amazon SageMaker, including SageMaker Unified Studio, is to make data and AI workers more productive by providing access to all your data and tools in a single development environment.

Building from a single data and AI development environment

Let’s explore a common business challenge: increasing revenue through better lead generation. Consider an organization implementing an intelligent digital assistant on their website to engage with customers—a process that traditionally requires multiple tools and data sources. With SageMaker Unified Studio, this entire process can now be carried out within a single data and AI development environment.

First, the data team uses the generative AI playground within SageMaker Unified Studio to quickly evaluate and select the best model for their customer interactions. They then create a project to house the tools and resources necessary for their use case and use Amazon Bedrock within the project to build and deploy a sophisticated virtual assistant that quickly begins qualifying leads through their website.

To identify the most promising opportunities, the team develops a segmentation strategy. The data engineer asks Amazon Q Developer to identify datasets that contain lead data and uses zero-ETL integrations to bring the data into SageMaker Lakehouse. The data analyst then discovers it and creates a comprehensive view of their market. They use the SQL query editor to build out marketing segments, which they then write back to SageMaker Lakehouse, where they are available to other team members.

Finally, the data scientist accesses the same dataset, which they use to train and deploy an automated lead scoring model using tools available from SageMaker AI. During the model development phase, they use Amazon Q Developer’s inline code authoring and troubleshooting capabilities to efficiently write error free-code in their JupyterLab notebook. The final model provides sales teams with the highest-value opportunities, which they can visualize in a business intelligence dashboard and take action on immediately.

Reducing time-to-value in a unified environment

What is remarkable about this example is that entire process happens in one integrated environment. Without SageMaker Unified Studio, the team would have had to work with multiple data sources, tools, and services, spending time learning multiple development environments, creating resources shares, and manually configuring access controls. The data engineer and data analyst would have worked in various data warehouses, data lakes, and analytics tools, the data scientist would have worked in an ML studio and notebook environment, and the application builder in a generative AI tool. Now, they’re able to build and collaborate with their data and tools available in one experience, dramatically reducing time-to-value.

That’s why we’re so excited about the next generation of Amazon SageMaker and the general availability of SageMaker Unified Studio. We believe that by putting everything you need for analytics and AI in one place, you can solve complex end-to-end problems more efficiently and get to innovative outcomes faster than ever before.

Getting started with SageMaker Unified Studio

To learn more, check out the following resources:


About the authors

G2 Krishnamoorthy is VP of Analytics, leading AWS data lake services, data integration, Amazon OpenSearch Service, and Amazon QuickSight. Prior to his current role, G2 built and ran the Analytics and ML Platform at Facebook/Meta, and built various parts of the SQL Server database, Azure Analytics, and Azure ML at Microsoft.

Rahul Pathak is VP of Relational Database Engines, leading Amazon Aurora, Amazon Redshift, and Amazon QLDB. Prior to his current role, he was VP of Analytics at AWS, where he worked across the entire AWS database portfolio. He has co-founded two companies, one focused on digital media analytics and the other on IP-geolocation.

Use DeepSeek with Amazon OpenSearch Service vector databases and Amazon SageMaker

Post Syndicated from Jon Handler original https://aws.amazon.com/blogs/big-data/use-deepseek-with-amazon-opensearch-service-vector-databases-and-amazon-sagemaker/

DeepSeek-R1 is a powerful and cost-effective AI model that excels at complex reasoning tasks. When combined with Amazon OpenSearch Service, it enables robust Retrieval Augmented Generation (RAG) applications. This post shows you how to set up RAG using DeepSeek-R1 on Amazon SageMaker with an OpenSearch Service vector database as the knowledge base. This example provides a solution for enterprises looking to enhance their AI capabilities.

OpenSearch Service provides rich capabilities for RAG use cases, as well as vector embedding-powered semantic search. You can use the flexible connector framework and search flow pipelines in OpenSearch to connect to models hosted by DeepSeek, Cohere, and OpenAI, as well as models hosted on Amazon Bedrock and SageMaker. In this post, we build a connection to DeepSeek’s text generation model, supporting a RAG workflow to generate text responses to user queries.

Solution overview

The following diagram illustrates the solution architecture.

In this walkthrough, you will use a set of scripts to create the preceding architecture and data flow. First, you will create an OpenSearch Service domain, and deploy DeepSeek-R1 to SageMaker. You will execute scripts to create an AWS Identity and Access Management (IAM) role for invoking SageMaker, and a role for your user to create a connector to SageMaker. You will create an OpenSearch connector and model that will enable the retrieval_augmented_generation processor within OpenSearch to execute a user query, perform a search, and use DeepSeek to generate a text response. You will create a connector to SageMaker with Amazon Titan Text Embeddings V2 to create embeddings for a set of documents with population statistics. Finally, you will execute the query to compare population growth in Miami and New York City.

Prerequisites

We’ve created and open-sourced a GitHub repo with all the code you need to follow along with the post and deploy it for yourself. You will need the following prerequisites:

Deploy DeepSeek on Amazon SageMaker

You will need to have or deploy DeepSeek with an Amazon SageMaker endpoint. To learn more about deploying DeepSeek-R1 on SageMaker, refer to Deploying DeepSeek-R1 Distill Model on AWS using Amazon SageMaker AI.

Create an OpenSearch Service domain

Refer to Create an Amazon OpenSearch Service domain for instructions on how to create your domain. Make note of the domain Amazon Resource Name (ARN) and domain endpoint, both of which can be found in the General information section of each domain on the OpenSearch Service console.

Download and prepare the code

Run the following steps from your local computer or workspace that has Python and git:

  1. If you haven’t already, clone the repo into a local folder using the following command:
git clone https://github.com/Jon-AtAWS/opensearch-examples.git
  1. Create a Python virtual environment:
cd opensearch-examples/opensearch-deepseek-rag
python -m venv .venv
source .venv/bin/activate
pip install -r requirements.txt

The example scripts use environment variables for setting some common parameters. Set these up now using the following commands. Be sure to update with your AWS Region, your SageMaker endpoint ARN and URL, your OpenSearch Service domain’s endpoint and ARN, and your domain’s primary user and password.
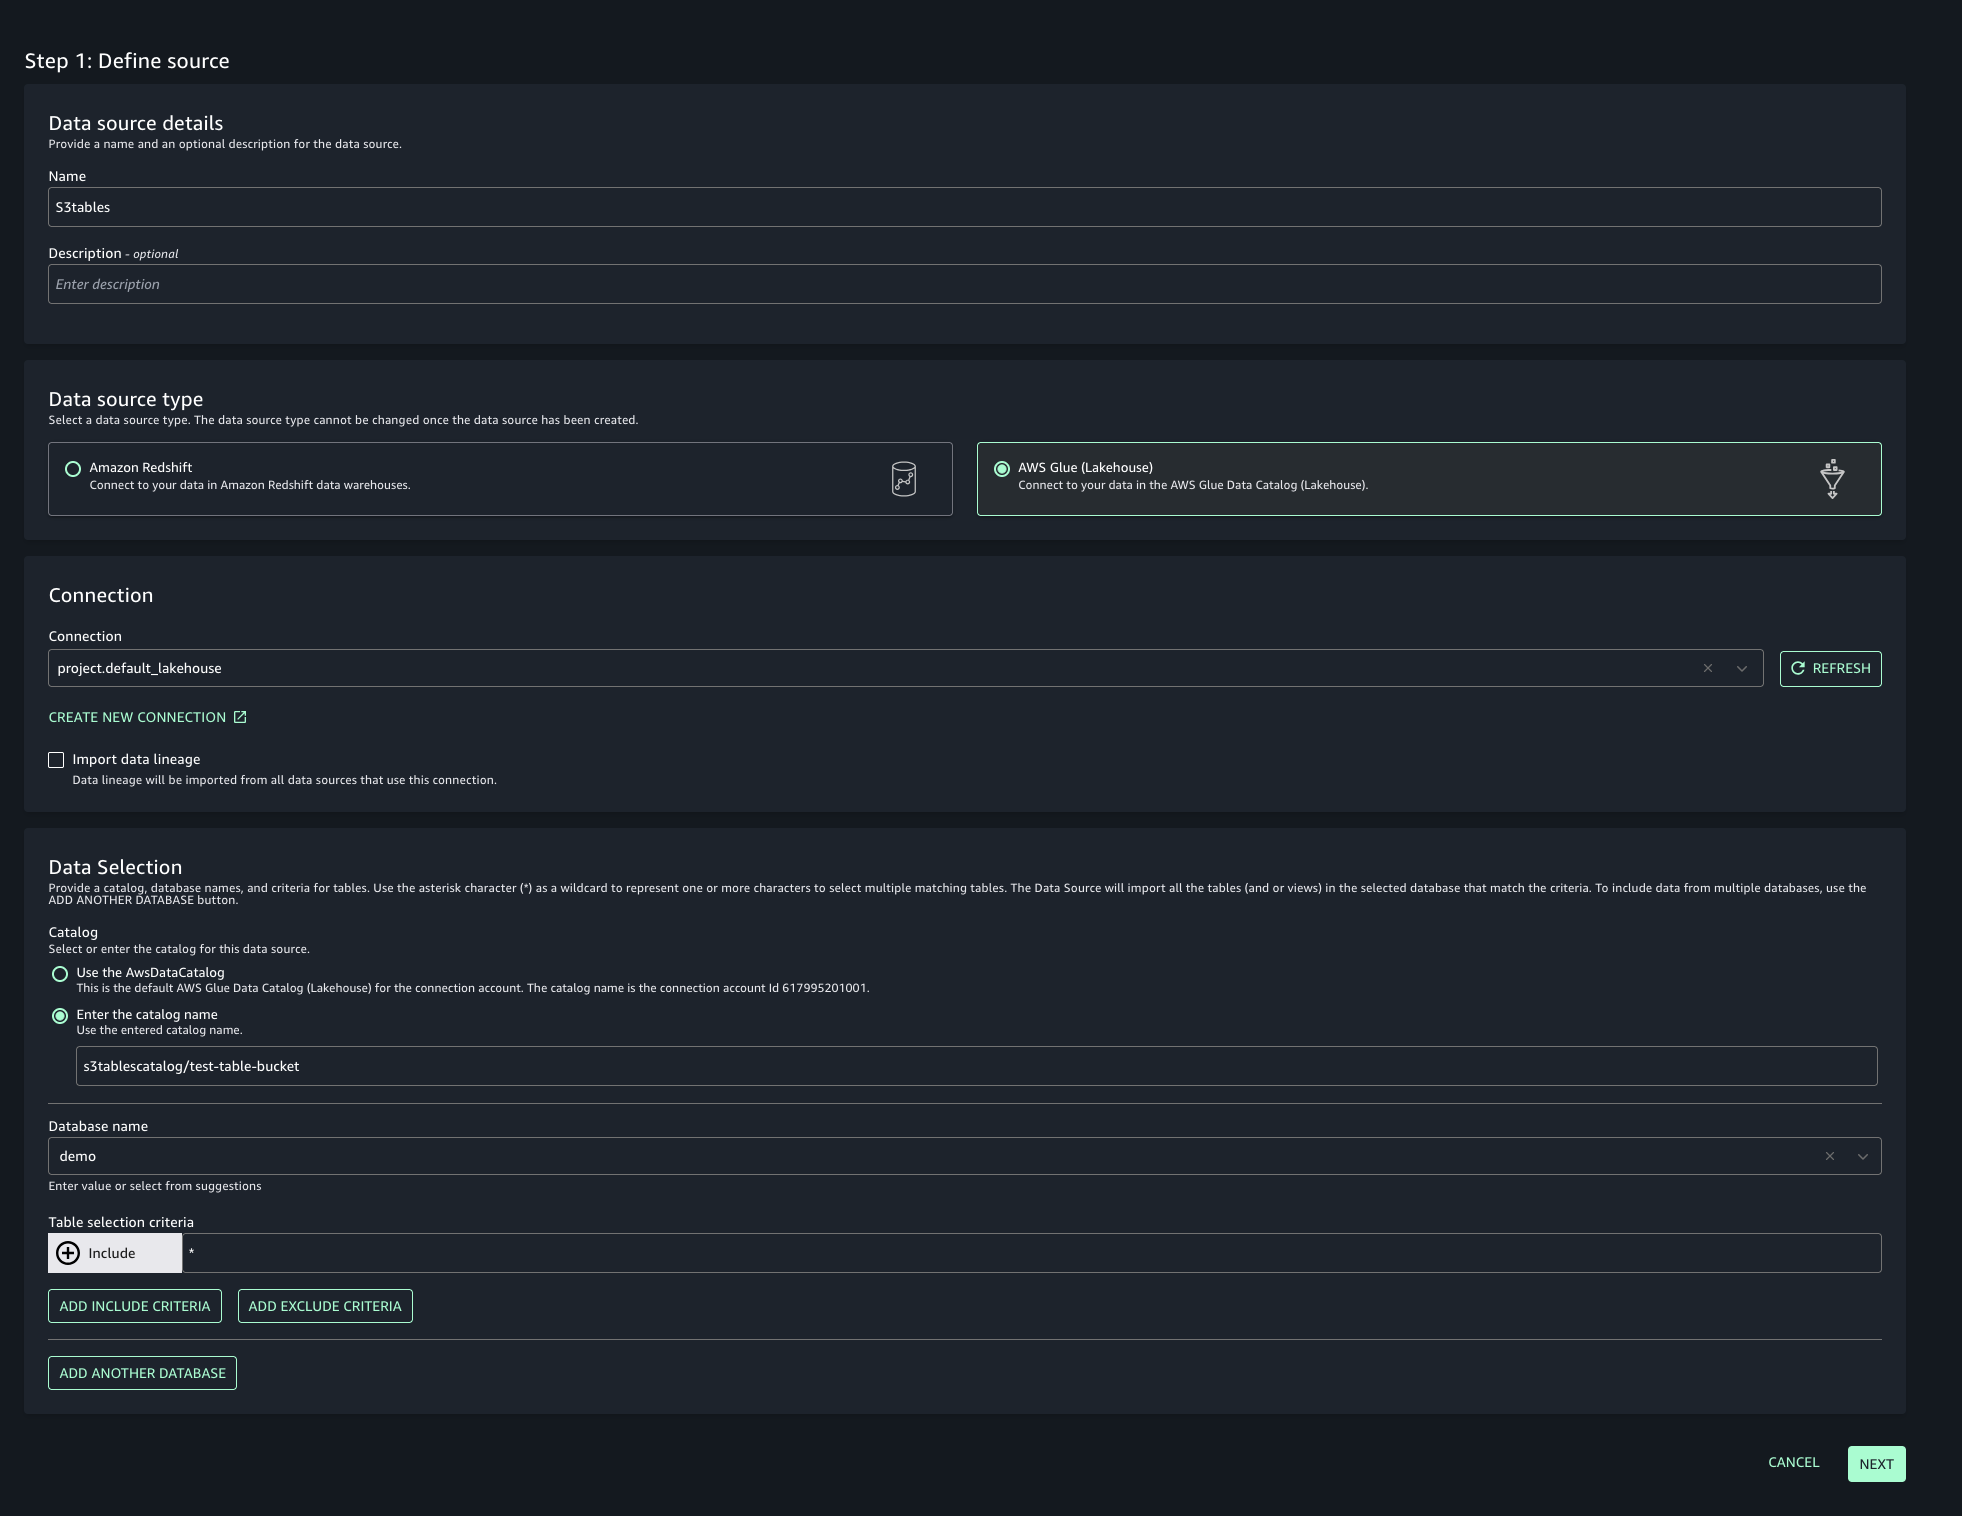
export DEEPSEEK_AWS_REGION='<your current region>'
export SAGEMAKER_MODEL_INFERENCE_ARN='<your SageMaker endpoint’s ARN>' 
export SAGEMAKER_MODEL_INFERENCE_ENDPOINT='<your SageMaker endpoint’s URL>'
export OPENSEARCH_SERVICE_DOMAIN_ARN='<your domain’s ARN>’
export OPENSEARCH_SERVICE_DOMAIN_ENDPOINT='<your domain’s API endpoint>'
export OPENSEARCH_SERVICE_ADMIN_USER='<your domain’s master user name>'
export OPENSEARCH_SERVICE_ADMIN_PASSWORD='<your domain’s master user password>'

You now have the code base and have your virtual environment set up. You can examine the contents of the opensearch-deepseek-rag directory. For clarity of purpose and reading, we’ve encapsulated each of seven steps in its own Python script. This post will guide you through running these scripts. We’ve also chosen to use environment variables to pass parameters between scripts. In an actual solution, you would encapsulate the code in classes and pass the values where needed. Coding this way is clearer, but is less efficient and doesn’t follow coding best practices. Use these scripts as examples to pull from.

First, you will set up permissions for your OpenSearch Service domain to connect to your SageMaker endpoint.

Set up permissions

You will create two IAM roles. The first will allow OpenSearch to call your SageMaker endpoint. The second will allow you to make the create connector API call to OpenSearch.

  1. Examine the code in create_invoke_role.py.
  2. Return to the command line, and execute the script:
python create_invoke_role.py
  1. Execute the command line from the script’s output to set the INVOKE_DEEPSEEK_ROLE environment variable.

You have created a role named invoke_deepseek_role, with a trust relationship for OpenSearch Service to assume the role, and with a permission policy that allows OpenSearch Service to invoke your SageMaker endpoint. The script outputs the ARNs for your role and policy and additionally a command line command to add the role to your environment. Execute that command before running the next script. Make a note of the role ARN in case you need to return at a later time.

Now you need to create a role for your user to be able to create a connector in OpenSearch Service.

  1. Examine the code in create_connector_role.py.
  2. Return to the command line and execute the script:
python create_connector_role.py
  1. Execute the command line from the script’s output to set the CREATE_DEEPSEEK_CONNECTOR_ROLE environment variable.

You have created a role named create_deepseek_connector_role, with a trust relationship with the current user and permissions to write to OpenSearch Service. You need these permissions to call the OpenSearch create_connector API, which packages a connection to a remote model host, DeepSeek in this case. The script prints the policy’s and role’s ARNs, and additionally a command line command to add the role to your environment. Execute that command before running the next script. Again, make note of the role ARN, just in case.

Now that you have your roles created, you will tell OpenSearch about them. The fine-grained access control feature includes an OpenSearch role, ml_full_access, that will allow authenticated entities to execute API calls within OpenSearch.

  1. Examine the code in setup_opensearch_security.py.
  2. Return to the command line and execute the script:
python setup_opensearch_security.py

You set up the OpenSearch Service security plugin to recognize two AWS roles: invoke_create_connector_role and LambdaInvokeOpenSearchMLCommonsRole. You will use the second role later, when you connect with an embedding model and load data into OpenSearch to use as a RAG knowledge base. Now that you have permissions in place, you can create the connector.

Create the connector

You create a connector with configuration that tells OpenSearch how to connect, provides credentials for the target model host, and provides prompt details. For more information, see Creating connectors for third-party ML platforms.

  1. Examine the code in create_connector.py.
  2. Return to the command line and execute the script:
python create_connector.py
  1. Execute the command line from the script’s output to set the DEEPSEEK_CONNECTOR_ID environment variable.

The script will create the connector to call the SageMaker endpoint and return the connector ID. The connector is an OpenSearch construct that tells OpenSearch how to connect to an external model host. You don’t use it directly; you create an OpenSearch model for that.

Create an OpenSearch model

When you work with machine learning (ML) models, in OpenSearch, you use OpenSearch’s ml-commons plugin to create a model. ML models are an OpenSearch abstraction that let you perform ML tasks like sending text for embeddings during indexing, or calling out to a large language model (LLM) to generate text in a search pipeline. The model interface provides you with a model ID in a model group that you then use in your ingest pipelines and search pipelines.

  1. Examine the code in create_deepseek_model.py.
  2. Return to the command line and execute the script:
python create_deepseek_model.py
  1. Execute the command line from the script’s output to set the DEEPSEEK_MODEL_ID environment variable.

You created an OpenSearch ML model group and model that you can use to create ingest and search pipelines. The _register API places the model in the model group and references your SageMaker endpoint through the connector (connector_id) you created.

Verify your setup

You can run a query to verify your setup and make sure that you can connect to DeepSeek on SageMaker and receive generated text. Complete the following steps:

  1. On the OpenSearch Service console, choose Dashboard under Managed clusters in the navigation pane.
  2. Choose your domain’s dashboard.

Amazon OpenSearch Service console on the AWS console showing where to click to reveal a domain’s details

  1. Choose the OpenSearch Dashboards URL (dual stack) link to open OpenSearch Dashboards.
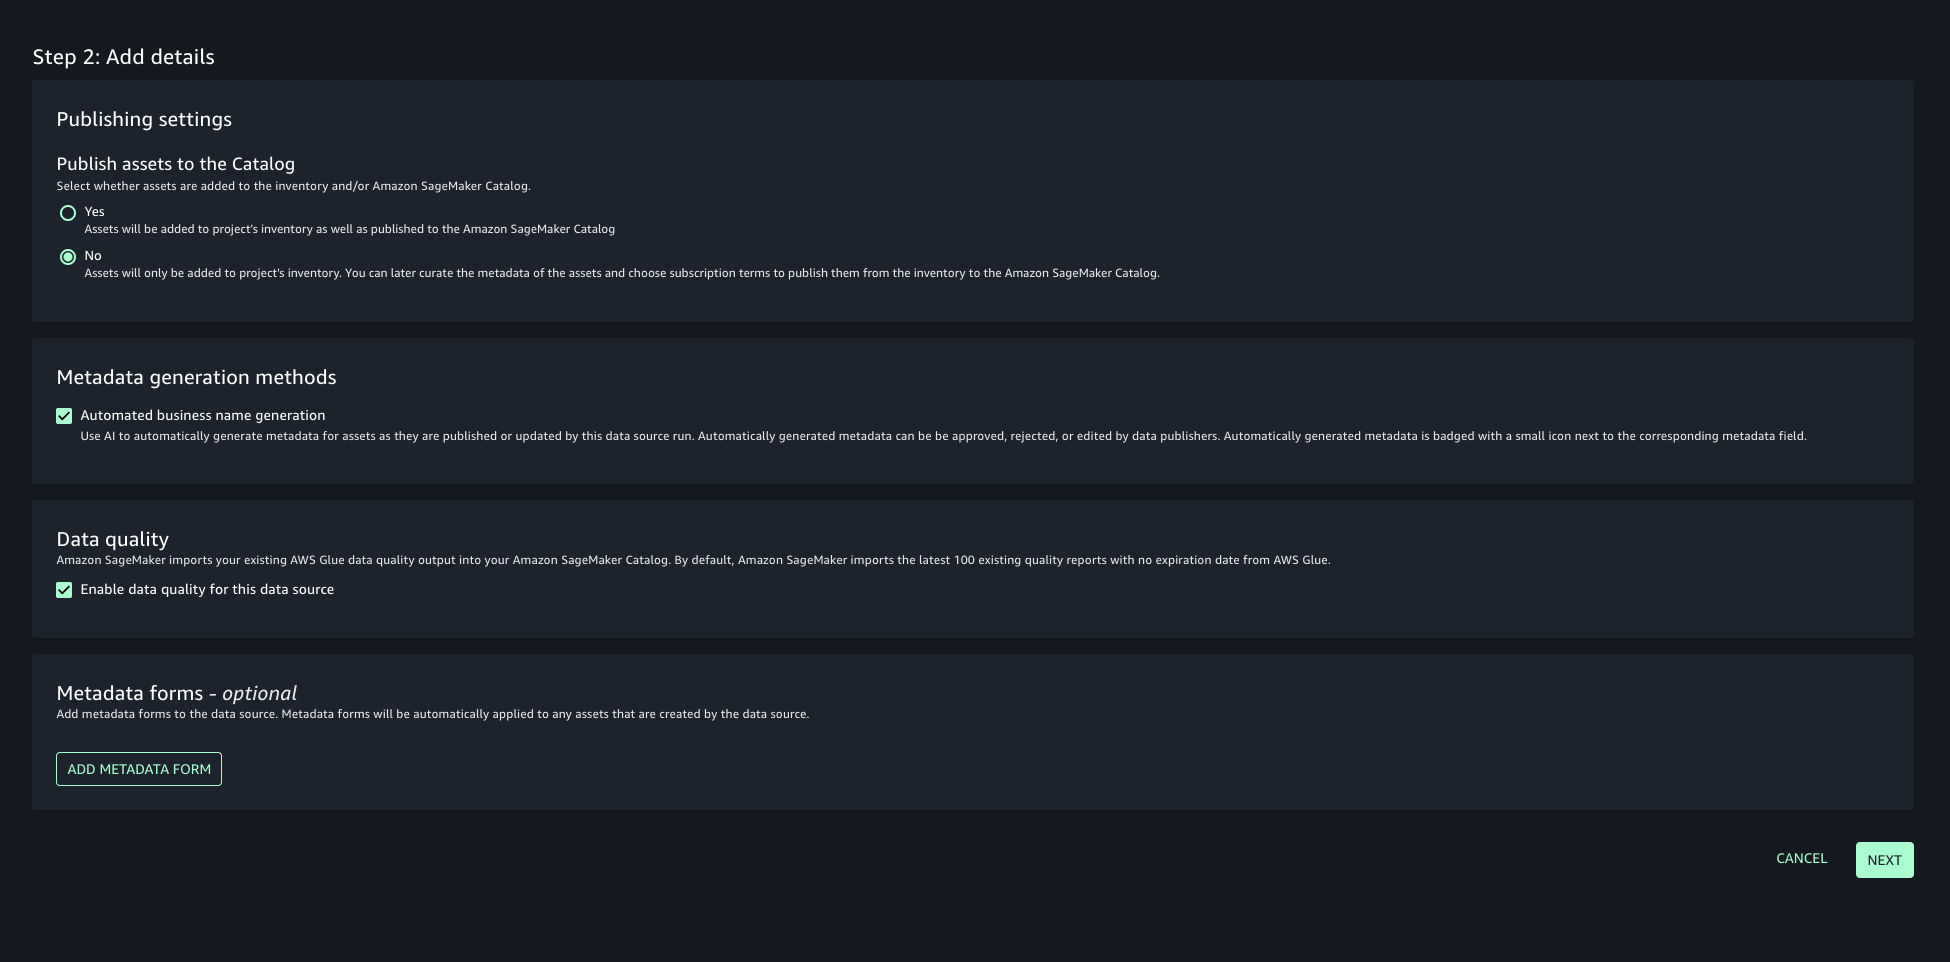
  2. Log in to OpenSearch Dashboards with your primary user name and password.
  3. Dismiss the welcome dialog by choosing Explore on my own.
  4. Dismiss the new look and feel dialog.
  5. Confirm the global tenant in the Select your tenant dialog.
  6. Navigate to the Dev Tools tab.
  7. Dismiss the welcome dialog.

You can also get to Dev Tools by expanding the navigation menu (three lines) to reveal the navigation pane, and scrolling down to Dev Tools.
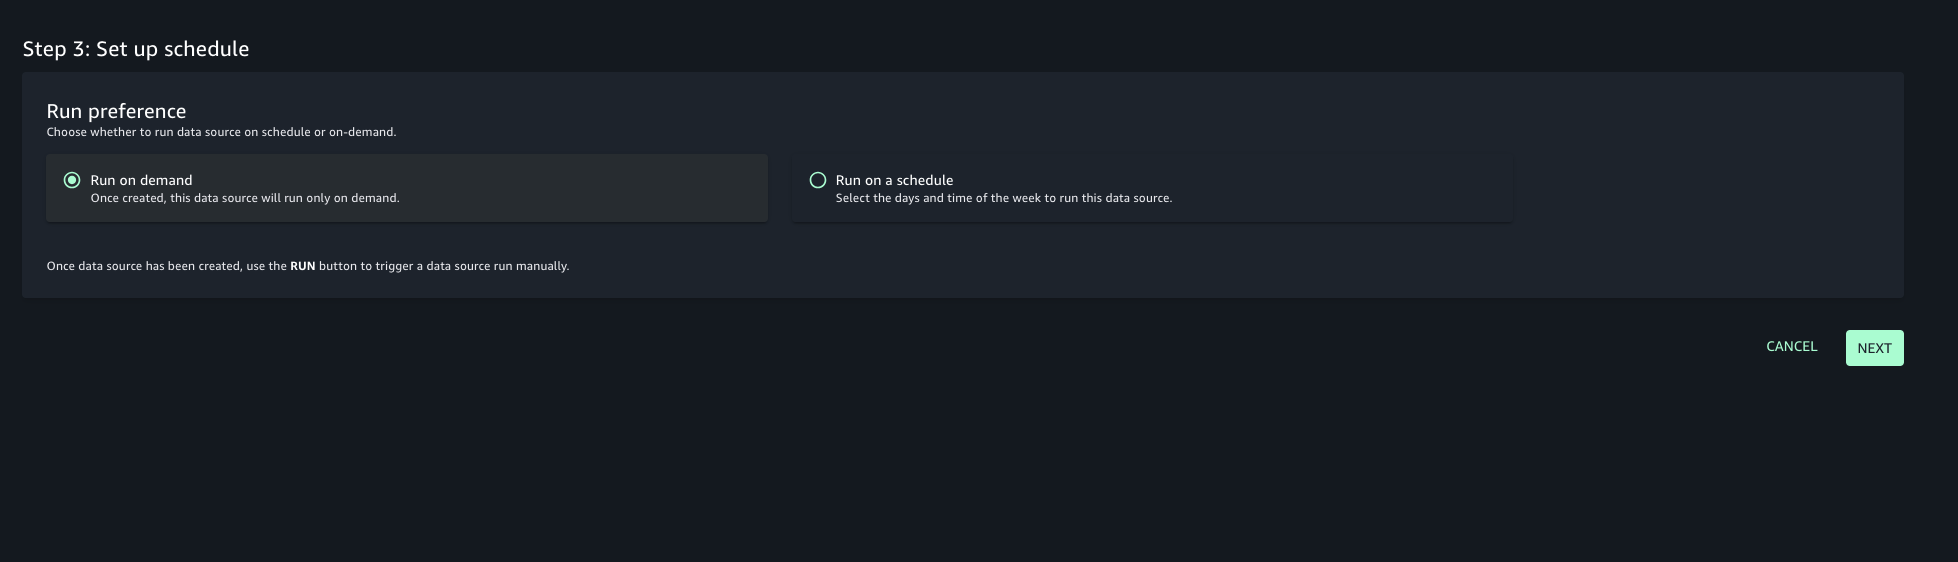
OpenSearch Dashboards home screen, with an indicator on where to click to open the Dev Tools tab

The Dev Tools page provides a left pane where you enter REST API calls. You execute the commands and the right pane shows the output of the command. Enter the following command in the left pane, replace your_model_id with the model ID you created, and run the command by placing the cursor anywhere in the command and choosing the run icon.
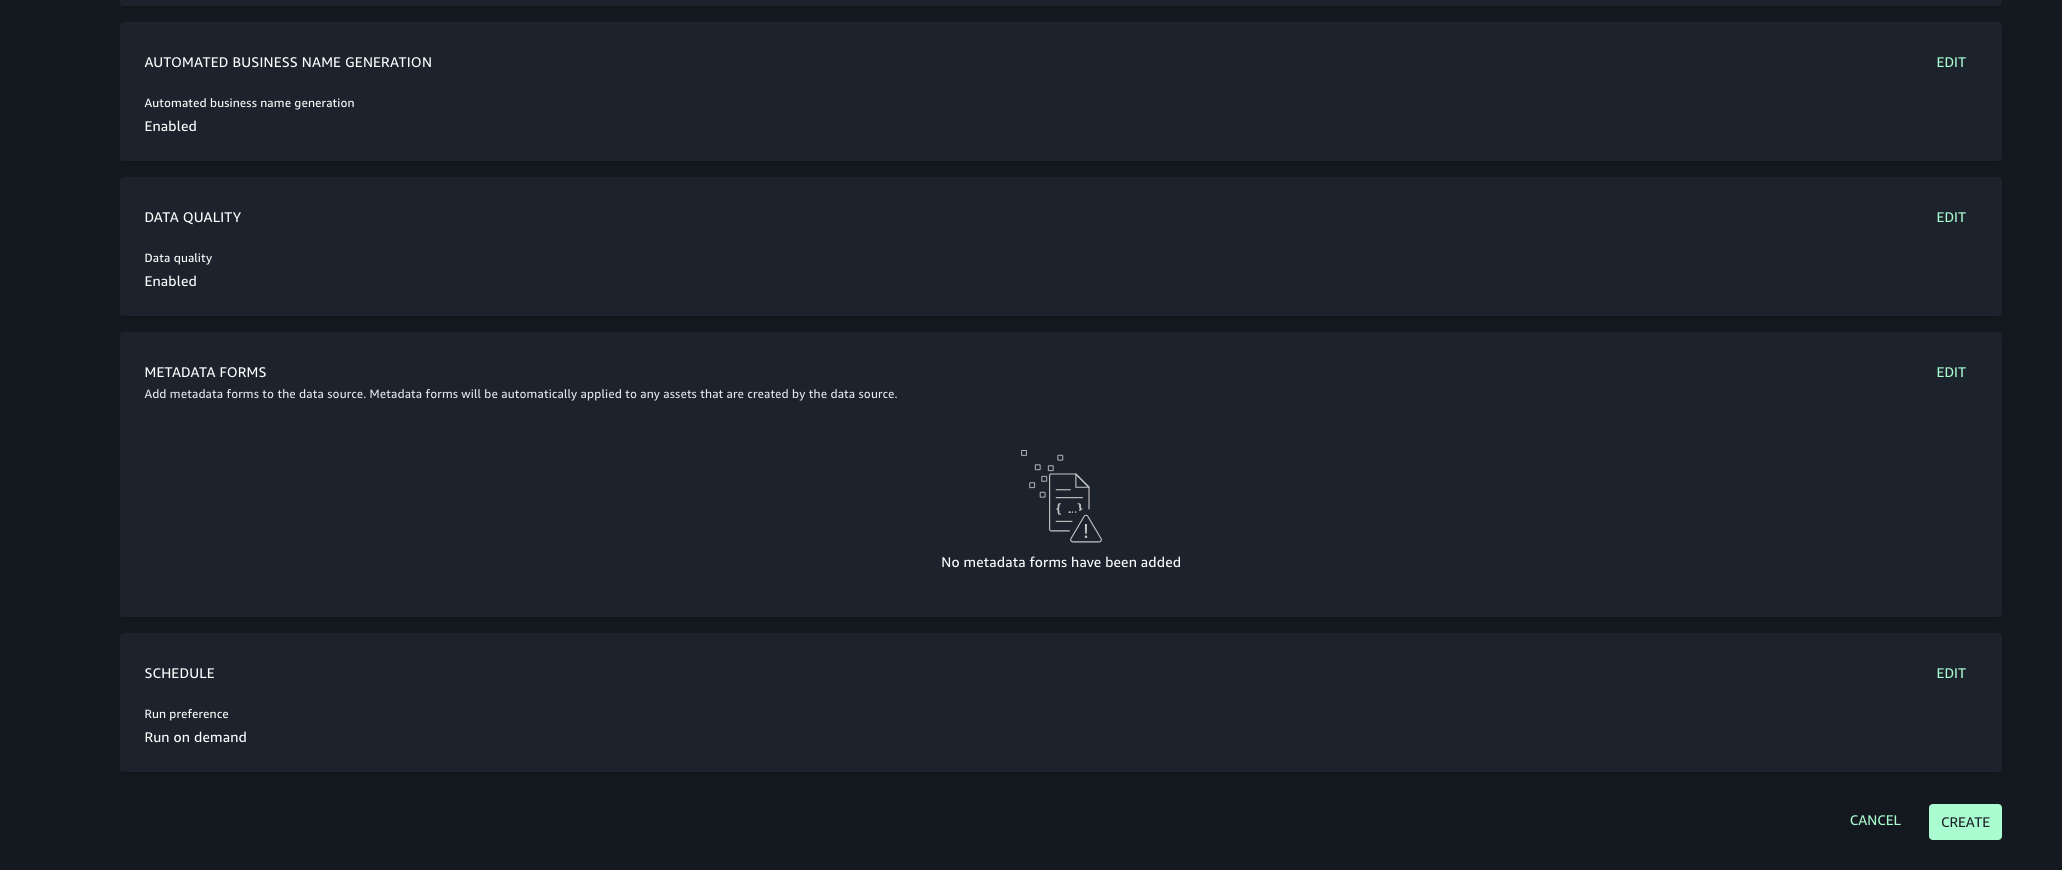
POST _plugins/_ml/models/<your model ID>/_predict{  "parameters": {    "inputs": "Hello"  }}

You should see output like the following screenshot.

Congratulations! You’ve now created and deployed an ML model that can use the connector you created to call to your SageMaker endpoint, and use DeepSeek to generate text. Next, you will use your model in an OpenSearch search pipeline to automate a RAG workflow.

Set up a RAG workflow

RAG is a way of adding information to the prompt so that the LLM generating the response is more accurate. An overall generative application like a chatbot orchestrates a call to external knowledge bases and augments the prompt with knowledge from those sources. We’ve created a small knowledge base comprising population information.

OpenSearch provides search pipelines, which are sets of OpenSearch search processors that are applied to the search request sequentially to build a final result. OpenSearch has processors for hybrid search, reranking, and RAG, among others. You define your processor and then send your queries to the pipeline. OpenSearch responds with the final result.

When you build a RAG application, you choose a knowledge base and a retrieval mechanism. In most cases, you will use an OpenSearch Service vector database as a knowledge base, performing a k-nearest neighbor (k-NN) search to incorporate semantic information in the retrieval with vector embeddings. OpenSearch Service provides integrations with vector embedding models hosted in Amazon Bedrock and SageMaker (among other options).

Make sure that your domain is running OpenSearch 2.9 or later, and that fine-grained access control is enabled for the domain. Then complete the following steps:

  1. On the OpenSearch Service console, choose Integrations in the navigation pane.
  2. Choose Configure domain under Integration with text embedding models through Amazon SageMaker.

  1. Choose Configure public domain.
  2. If you created a virtual private cloud (VPC) domain instead, choose Configure VPC domain.

You will be redirected to the AWS CloudFormation console.

  1. For Amazon OpenSearch Endpoint, enter your endpoint.
  2. Leave everything else as default values.

The CloudFormation stack requires a role to create a connector to the all-MiniLM-L6-v2 model, hosted on SageMaker, called LambdaInvokeOpenSearchMLCommonsRole. You enabled access for this role when you ran setup_opensearch_security.py. If you changed the name in that script, be sure to change it in the Lambda Invoke OpenSearch ML Commons Role Name field.

  1. Select I acknowledge that AWS CloudFormation might create IAM resources with custom names, and choose Create stack.

For simplicity, we’ve elected to use the open source all-MiniLM-L6-v2 model, hosted on SageMaker for embedding generation. To achieve high search quality for production workloads, you should fine-tune lightweight models like all-MiniLM-L6-v2, or use OpenSearch Service integrations with models such as Cohere Embed V3 on Amazon Bedrock or Amazon Titan Text Embedding V2, which are designed to deliver high out-of-the-box quality.

Wait for CloudFormation to deploy your stack and the status to change to Create_Complete.

  1. Choose the stack’s Outputs tab on the CloudFormation console and copy the value for ModelID.

The AWS CloudFormation console showing the template results for the integration template and where to find the model ID

You will use this model ID to connect with your embedding model.

  1. Examine the code in load_data.py.
  2. Return to the command line and set an environment variable with the model ID of the embedding model:
export EMBEDDING_MODEL_ID='<the model ID from CloudFormation’s output>'
  1. Execute the script to load data into your domain:
python load_data.py

The script creates the population_data index and an OpenSearch ingest pipeline that calls SageMaker using the connector referenced by the embedding model ID. The ingest pipeline’s field mapping tells OpenSearch the source and destination fields for each document’s embedding.

Now that you have your knowledge base prepared, you can run a RAG query.

  1. Examine the code in run_rag.py.
  2. Return to the command line and execute the script:
python run_rag.py

The script creates a search pipeline with an OpenSearch retrieval_augmented_generation processor. The processor automates running an OpenSearch k-NN query to retrieve relevant information and adding that information to the prompt. It uses the generation_model_id and connector to the DeepSeek model on SageMaker to generate a text response for the user’s question. The OpenSearch neural query (line 55 of run_rag.py) takes care of generating the embedding for the k-NN query using the embedding_model_id. In the ext section of the query, you provide the user’s question for the LLM. The llm_model is set to bedrock/claude because the parameterization and actions are the same as they are for DeepSeek. You’re still using DeepSeek to generate text.

Examine the output from OpenSearch Service. The user asked the question “What’s the population increase of New York City from 2021 to 2023? How is the trending comparing with Miami?” The first portion of the result shows the hits—documents OpenSearch retrieved from the semantic query—as the population statistics for New York City and Miami. The next section of the response includes the prompt, as well as DeepSeek’s answer.

Okay, so I need to figure out the population increase of New York City from 2021 to 2023 and compare it with Miami's growth. 
Let me start by looking at the data provided in the search results.
From SEARCH RESULT 2, I see that in 2021, NYC had a population of 18,823,000. 
In 2022, it was 18,867,000, and in 2023, it's 18,937,000. 
So, the increase from 2021 to 2022 is 18,867,000 - 18,823,000 = 44,000. 
Then from 2022 to 2023, it's 18,937,000 - 18,867,000 = 70,000. 
Adding those together, the total increase from 2021 to 2023 is 44,000 + 70,000 = 114,000.
Now, looking at Miami's data in SEARCH RESULT 1. In 2021, Miami's population was 6,167,000, in 2022 it was 6,215,000, and in 2023 it's 6,265,000. 
The increase from 2021 to 2022 is 6,215,000 - 6,167,000 = 48,000. From 2022 to 2023, it's 6,265,000 - 6,215,000 = 50,000. 
So, the total increase is 48,000 + 50,000 = 98,000.Comparing the two, NYC's increase of 114,000 is higher than Miami's 98,000. 
So, NYC's population increased more over that period."

Congratulations! You’ve connected to an embedding model, created a knowledge base, and used that knowledge base, along with DeepSeek, to generate a text response to a question on population changes in New York City and Miami. You can adapt the code from this post to create your own knowledge base and run your own queries.

Clean up

To avoid incurring additional charges, clean up the resources you deployed:

  1. Delete the SageMaker deployment of DeepSeek. For instructions, see Cleaning Up.
  2. If your Jupyter notebook has lost context, you can delete the endpoint:
    1. On the SageMaker console, under Inference in the navigation pane, choose Endpoints.
    2. Select your endpoint and choose Delete.
  3. Delete the CloudFormation template for connecting to SageMaker for the embedding model.
  4. Delete the OpenSearch Service domain you created.

Conclusion

The OpenSearch connector framework is a flexible way for you to access models you host on other platforms. In this example, you connected to the open source DeepSeek model that you deployed on SageMaker. DeepSeek’s reasoning capabilities, augmented with a knowledge base in the OpenSearch Service vector engine, enabled it to answer a question comparing population growth in New York and Miami.

Find out more about AI/ML capabilities of OpenSearch Service, and let us know how you are using DeepSeek and other generative models to build!


About the Authors

Jon Handler is the Director of Solutions Architecture for Search Services at Amazon Web Services, based in Palo Alto, CA. Jon works closely with OpenSearch and Amazon OpenSearch Service, providing help and guidance to a broad range of customers who have search and log analytics workloads for OpenSearch. Prior to joining AWS, Jon’s career as a software developer included four years of coding a large-scale, eCommerce search engine. Jon holds a Bachelor of the Arts from the University of Pennsylvania, and a Master of Science and a Ph. D. in Computer Science and Artificial Intelligence from Northwestern University.

Yaliang Wu is a Software Engineering Manager at AWS, focusing on OpenSearch projects, machine learning, and generative AI applications.