Tag Archives: artificial intelligence

Agentic application modernization at scale with Strands and Amazon Transform custom

Post Syndicated from Kanishk Mahajan original https://aws.amazon.com/blogs/devops/use-generative-ai-agents-for-application-modernization-at-scale-with-strands-amazon-transform-custom-and-amazon-bedrock-agentcore/

Introduction

Modernizing applications by upgrading language runtimes, migrating SDKs, and refactoring frameworks is important for cloud adoption but can be labor-intensive at scale. Each repository requires analysis of dependencies and transformation needs; custom transformation logic must be built and validated, and changes are often executed sequentially across codebases. If you have hundreds of applications, this stretches timelines from months to years, while introducing inconsistency across your teams.

To address this, Amazon Web Services (AWS) provides a composable set of building blocks. AWS Transform custom enables reusable, CLI-driven code transformations for upgrading runtimes, SDKs, and frameworks consistently across large portfolios. Strands Agents provides a framework for building multi-agent systems that coordinate complex transformation workflows. Amazon Bedrock AgentCore delivers the managed runtime, memory, and observability to operate these agents reliably in production. Together, they replace manual, sequential modernization with an intelligent, automated approach that scales.

In this post, we show you how to combine these services to build a generative AI–powered, agentic modernization system that can automatically analyze application repositories, determine required changes, create missing transformations, and execute them in parallel at scale.

Solution overview

The solution uses an agentic architecture that separates intelligent decision-making from deterministic execution, enabling automation at scale while maintaining consistency and control. In this post, you will build an AI-driven application modernization system that demonstrates how multi-agent workflows can be applied to large-scale code transformation scenarios. You interact with the system through a React-based frontend or API interface, submitting individual repositories or batch workloads via CSV inputs. Requests are processed asynchronously through an API layer that invokes an orchestrator agent running on Amazon Bedrock AgentCore, which coordinates specialized agents to analyze codebases, identify transformation requirements, and manage execution workflows. Results are stored and surfaced through the interface, allowing users to track progress and review outputs in real time.The workflow begins with repository analysis, where the system inspects application codebases to identify languages, dependencies, and required upgrades such as runtime version changes or SDK migrations. Based on this analysis, the system maps each application to an existing transformation when available. If no suitable transformation exists, a creation agent dynamically generates one using natural language instructions and publishes it to a centralized registry for reuse, creating a continuously improving system where transformation coverage expands over time.

Once transformations are identified or created, an execution agent runs them at scale by invoking AWS Batch jobs that execute the AWS Transform custom CLI, enabling parallel processing across multiple repositories. The orchestrator coordinates all agents, maintains workflow state using Amazon Bedrock AgentCore Memory, and ensures reliable execution through structured task decomposition, tool invocation, and error handling. While the example focuses on application re-platforming, the same architectural pattern can be applied to other large-scale code analysis and automation workflows.

The following architecture diagram (Figure 1) illustrates the various components of our solution as outlined in this section:architecture diagram describing the multi agent strands and agentcore deployment

Figure 1: AWS Transform custom Agentic Orchestration Architecture using Strands agents and Amazon Bedrock AgentCore

Prerequisites

Complete the following prerequisites:

  1. Install the AWS Command Line Interface (AWS CLI).
  2. Install the AWS SAM CLI v1.100.0+
  3. Install Docker v20.x+.
  4. Install Node.js v18.x+
  5. Install Python v3.11+
  6. Install the AWS CDK CLI
  7. Enable access to a Bedrock model for the orchestrator in your deployment region. The default model can be configured through the Amazon Bedrock model access console. To use a different model, set `BEDROCK_MODEL_ID` in `deployment/config.env` before Step 3 and enable access to that model instead. Model access approval can take a few minutes in some accounts, so complete this step before deploying.

Dependencies

The Strands Agents implementation has the following dependencies that are packaged in the DockerFile:

  1. Strands multi-agent framework: strands-agents
  2. Strands agent tools and utilities: strands-agents-tools
  3. HTTP library for API calls: requests
  4. Amazon Bedrock AgentCore SDK: bedrock-agentcore
  5. AWS SDK for Python: boto3

Deploy the solution

The solution is available for download on the GitHub repo. This post walks through the CDK + SAM deployment path (Option A in the repository README). The repository also includes a CDK-only option (Option B); see the repository README for details.

Step 1: Clone the repository

git clone https://github.com/aws-samples/aws-transform-custom-samples.git

cd aws-transform-custom-samples/agentic-atx-platform

Step 2: Configure AWS Credentials

# Configure AWS CLI

aws configure

# Verify credentials

aws sts get-caller-identity

Step 3: Deploy ATX CLI Container image and frontend using AWS CDK

# Copy configuration template (defaults work for most setups; edit only to change region or Bedrock model)

cd deployment

cp config.env.template config.env

# Authenticate with Amazon ECR Public (required for the Docker base image pull)

aws ecr-public get-login-password --region us-east-1 | docker login --username AWS --password-stdin public.ecr.aws

# Build the UI placeholder so CDK’s UI stack has ui/dist/ to deploy

cd ../ui && npm install && npx vite build

# Install CDK dependencies and bootstrap (run once per account/region)

cd ../cdk

npm install cdk bootstrap

# Build TypeScript and deploy the three stacks

npx tsc

CDK_DEFAULT_ACCOUNT=$(aws sts get-caller-identity --query Account --output text)

cdk deploy AtxContainerStack AtxInfrastructureStack AtxUiStack --require-approval never

# Note for accounts without a default VPC , pass the VPC context flags to `cdk deploy`:

cdk deploy AtxContainerStack AtxInfrastructureStack AtxUiStack --require-approval never

cdk deploy AtxContainerStack AtxInfrastructureStack AtxUiStack --require-approval never -c existingVpcId=vpc-xxx -c existingSubnetIds=subnet-aaa,subnet-bbb -c existingSecurityGroupId=sg-ccc

# Subnets must be public (auto-assign public IP enabled) or private with a NAT gateway so Fargate tasks can reach Amazon ECR, Amazon S3, and Git repositories.

Step 4: Deploy Strands Agents to AgentCore runtime using AWS SAM

cd ../sam./deploy.sh

# Invoke the deploy Lambda to create the AgentCore Runtime via the bedrock-agentcore-control SDK (takes 2-5 minutes)

aws lambda invoke --function-name atx-deploy-agentcore \ --region us-east-1 \ --cli-binary-format raw-in-base64-out \ --payload '{"action":"deploy"}' \ --cli-read-timeout 900 /tmp/deploy-output.jsoncat /tmp/deploy-output.json

Step 5: Wire the AgentCore runtime ARN into the async invoke Lambda

ACCOUNT_ID=$(aws sts get-caller-identity --query Account --output text)

RUNTIME_ARN=$(python3 -c "import json; print(json.loads(json.load(open('/tmp/deploy-output.json'))['body'])['runtime_arn'])")aws lambda update-function-configuration \ --function-name atx-async-invoke-agent \ --region us-east-1 \ --environment "Variables={AGENT_RUNTIME_ARN=${RUNTIME_ARN},RESULT_BUCKET=atx-custom-output-${ACCOUNT_ID},JOBS_TABLE=atx-transform-jobs}"

Step 6: Rebuild and deploy the frontend with AgentCore API endpoint

# Update the React application with the deployed API endpoint and redeploy it.

API_URL=$(aws cloudformation describe-stacks \ --stack-name AtxAgentCoreSAM \ --region us-east-1 \ --query 'Stacks[0].Outputs[?OutputKey==`ApiEndpoint`].OutputValue' \ --output text)

cd ../ui

VITE_API_ENDPOINT=$API_URL npx vite build./deploy-aws.sh

# This rebuilds the React application with the correct API endpoint, uploads it to Amazon S3, and invalidates the Amazon CloudFront distribution.

Step 7: Access the application

# After deployment completes, retrieve the CloudFront distribution URL from the AWS CloudFormation outputs and open it in your browser to access the application UI.

aws cloudformation describe-stacks \ --stack-name AtxUiStack \ --region us-east-1 \ --query 'Stacks[0].Outputs[?OutputKey==`WebsiteUrl`].OutputValue' \ --output text

Using the application

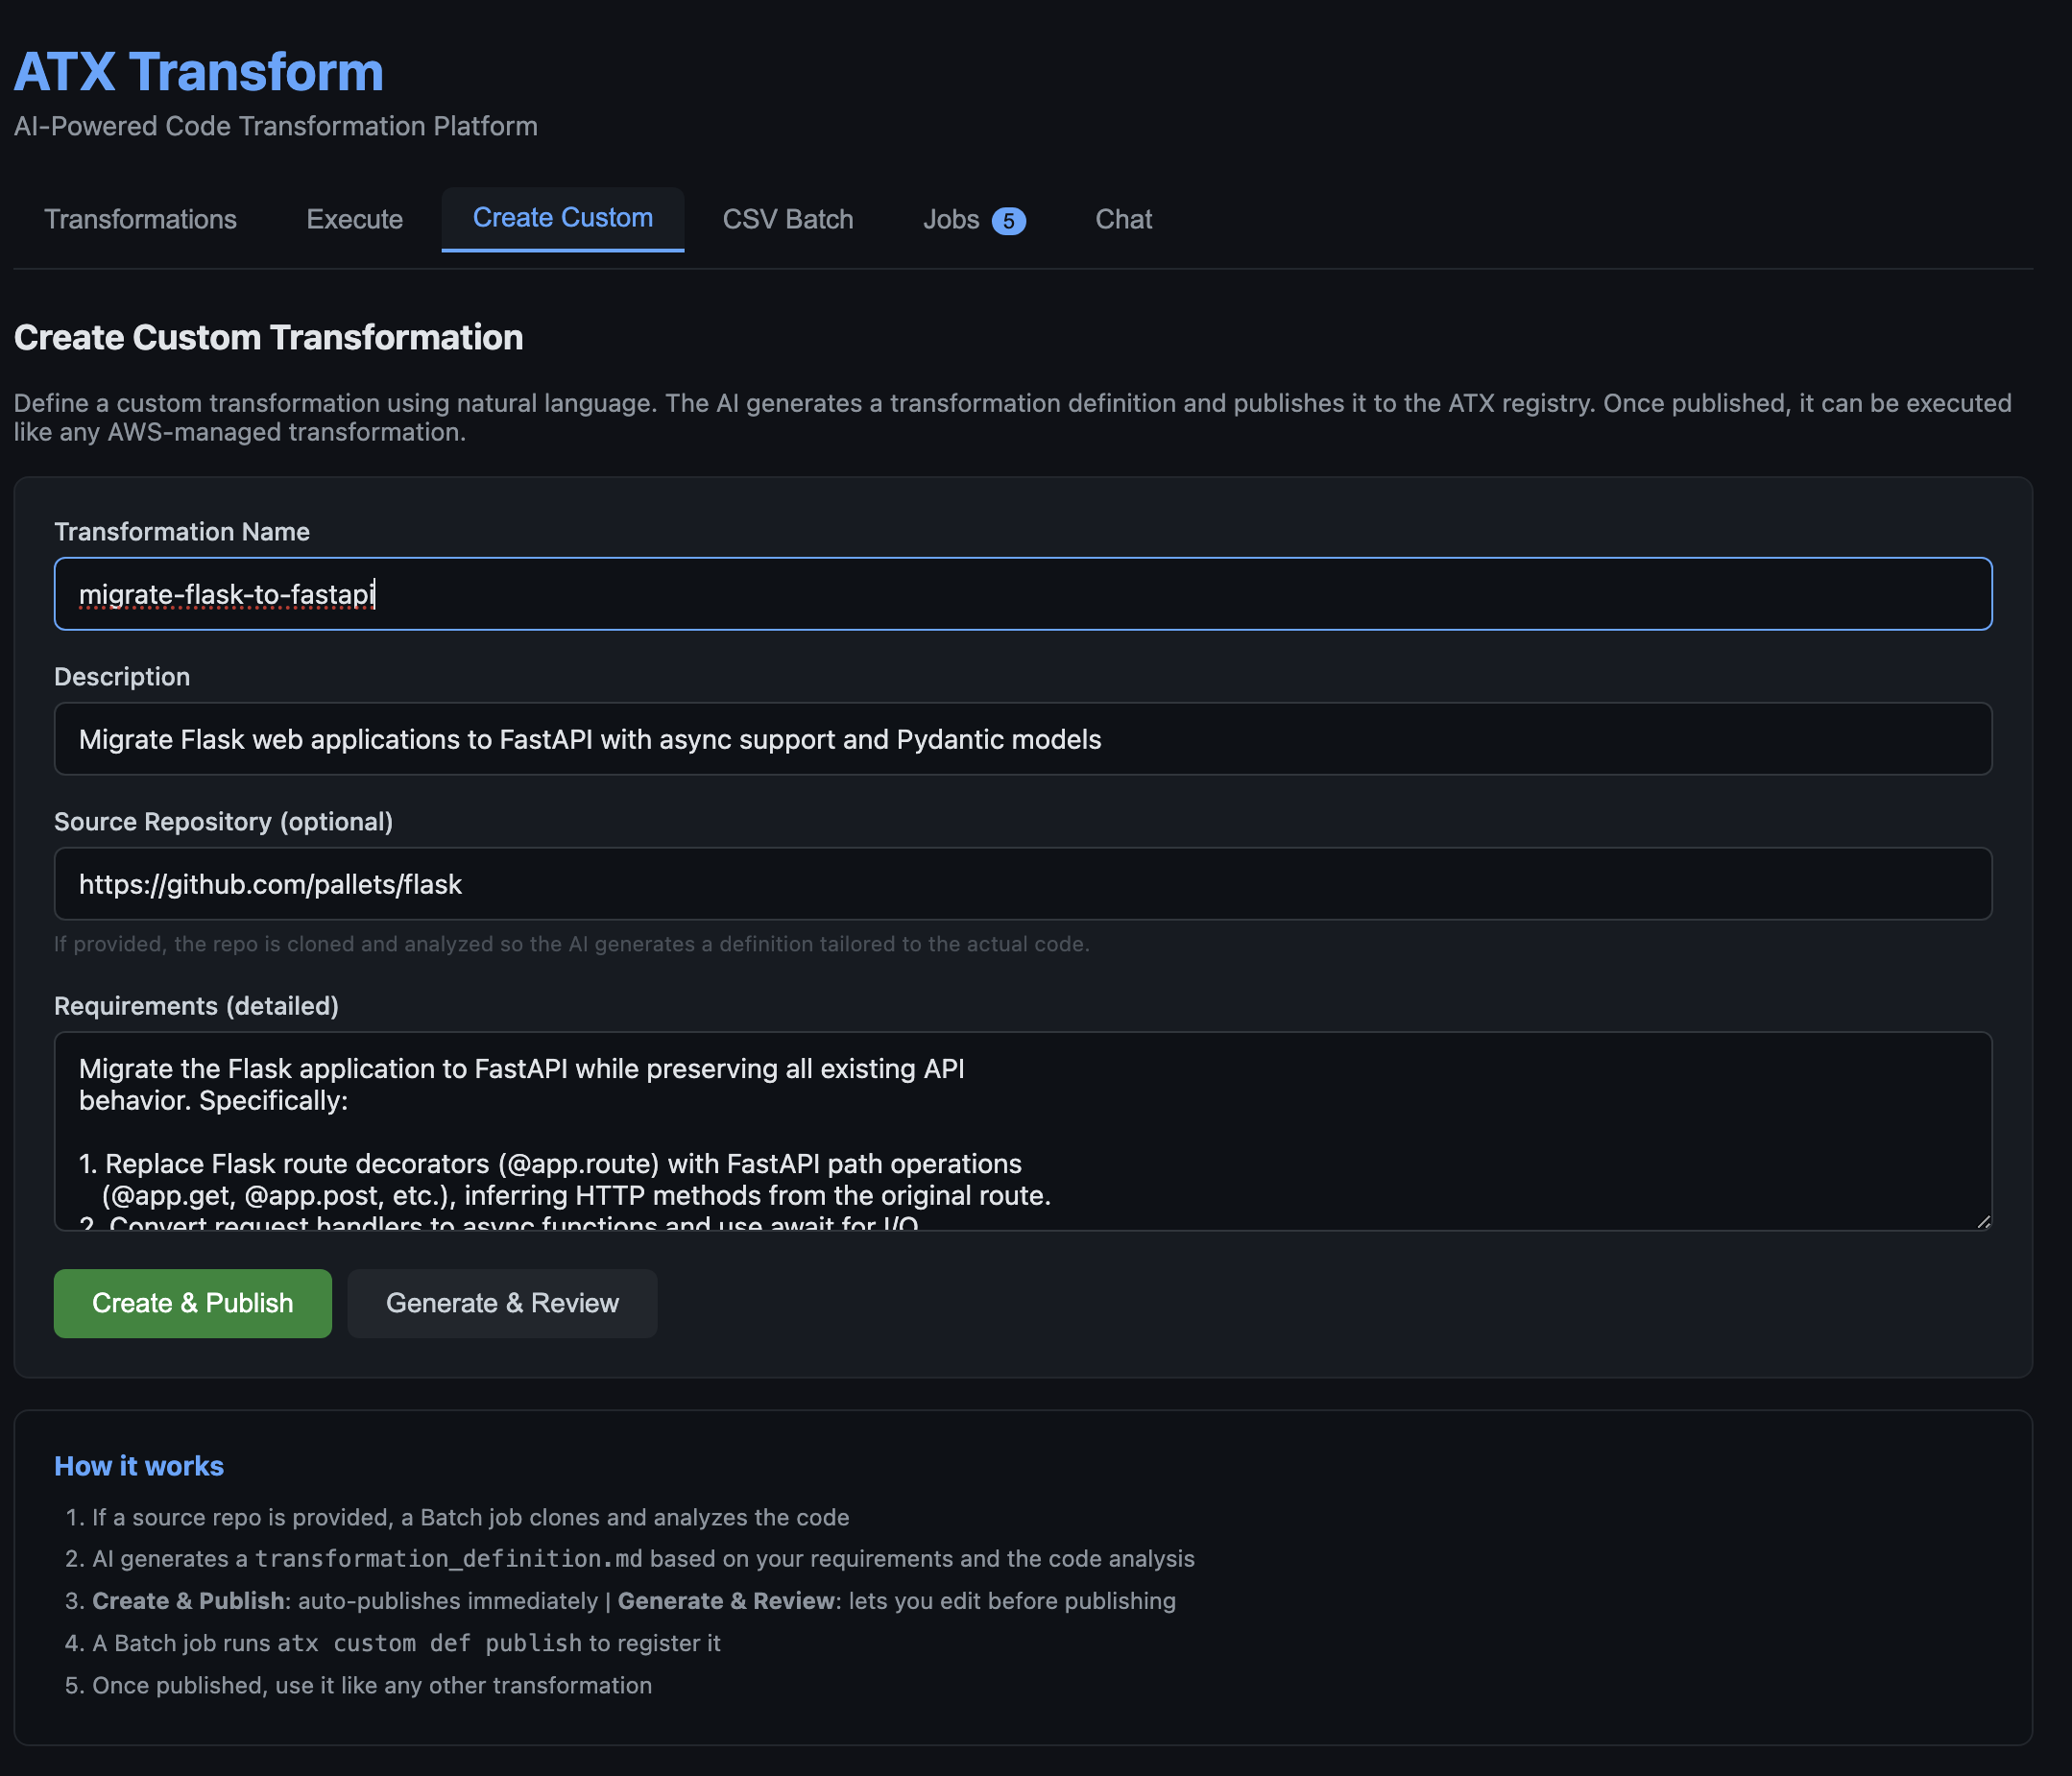
The UI exposes five tabs covering the complete modernization workflow: browsing available transformations, executing a transformation on a single repository, creating a new custom transformation with natural language, batch-processing a CSV of repositories, and tracking job status. This section walks through two of the most common flows.

Create a custom transformation from natural language

Open the Create Custom tab, describe the transformation in plain English (for example, “Upgrade Spring Boot 2 applications to Spring Boot 3”), and optionally provide a reference repository URL. The creation agent analyzes the source, generates a transformation definition, and publishes it to the ATX registry for reuse across the portfolio.

Describing a custom transformation in plain English. The form accepts a name, description, optional reference repository, and natural-language requirements.

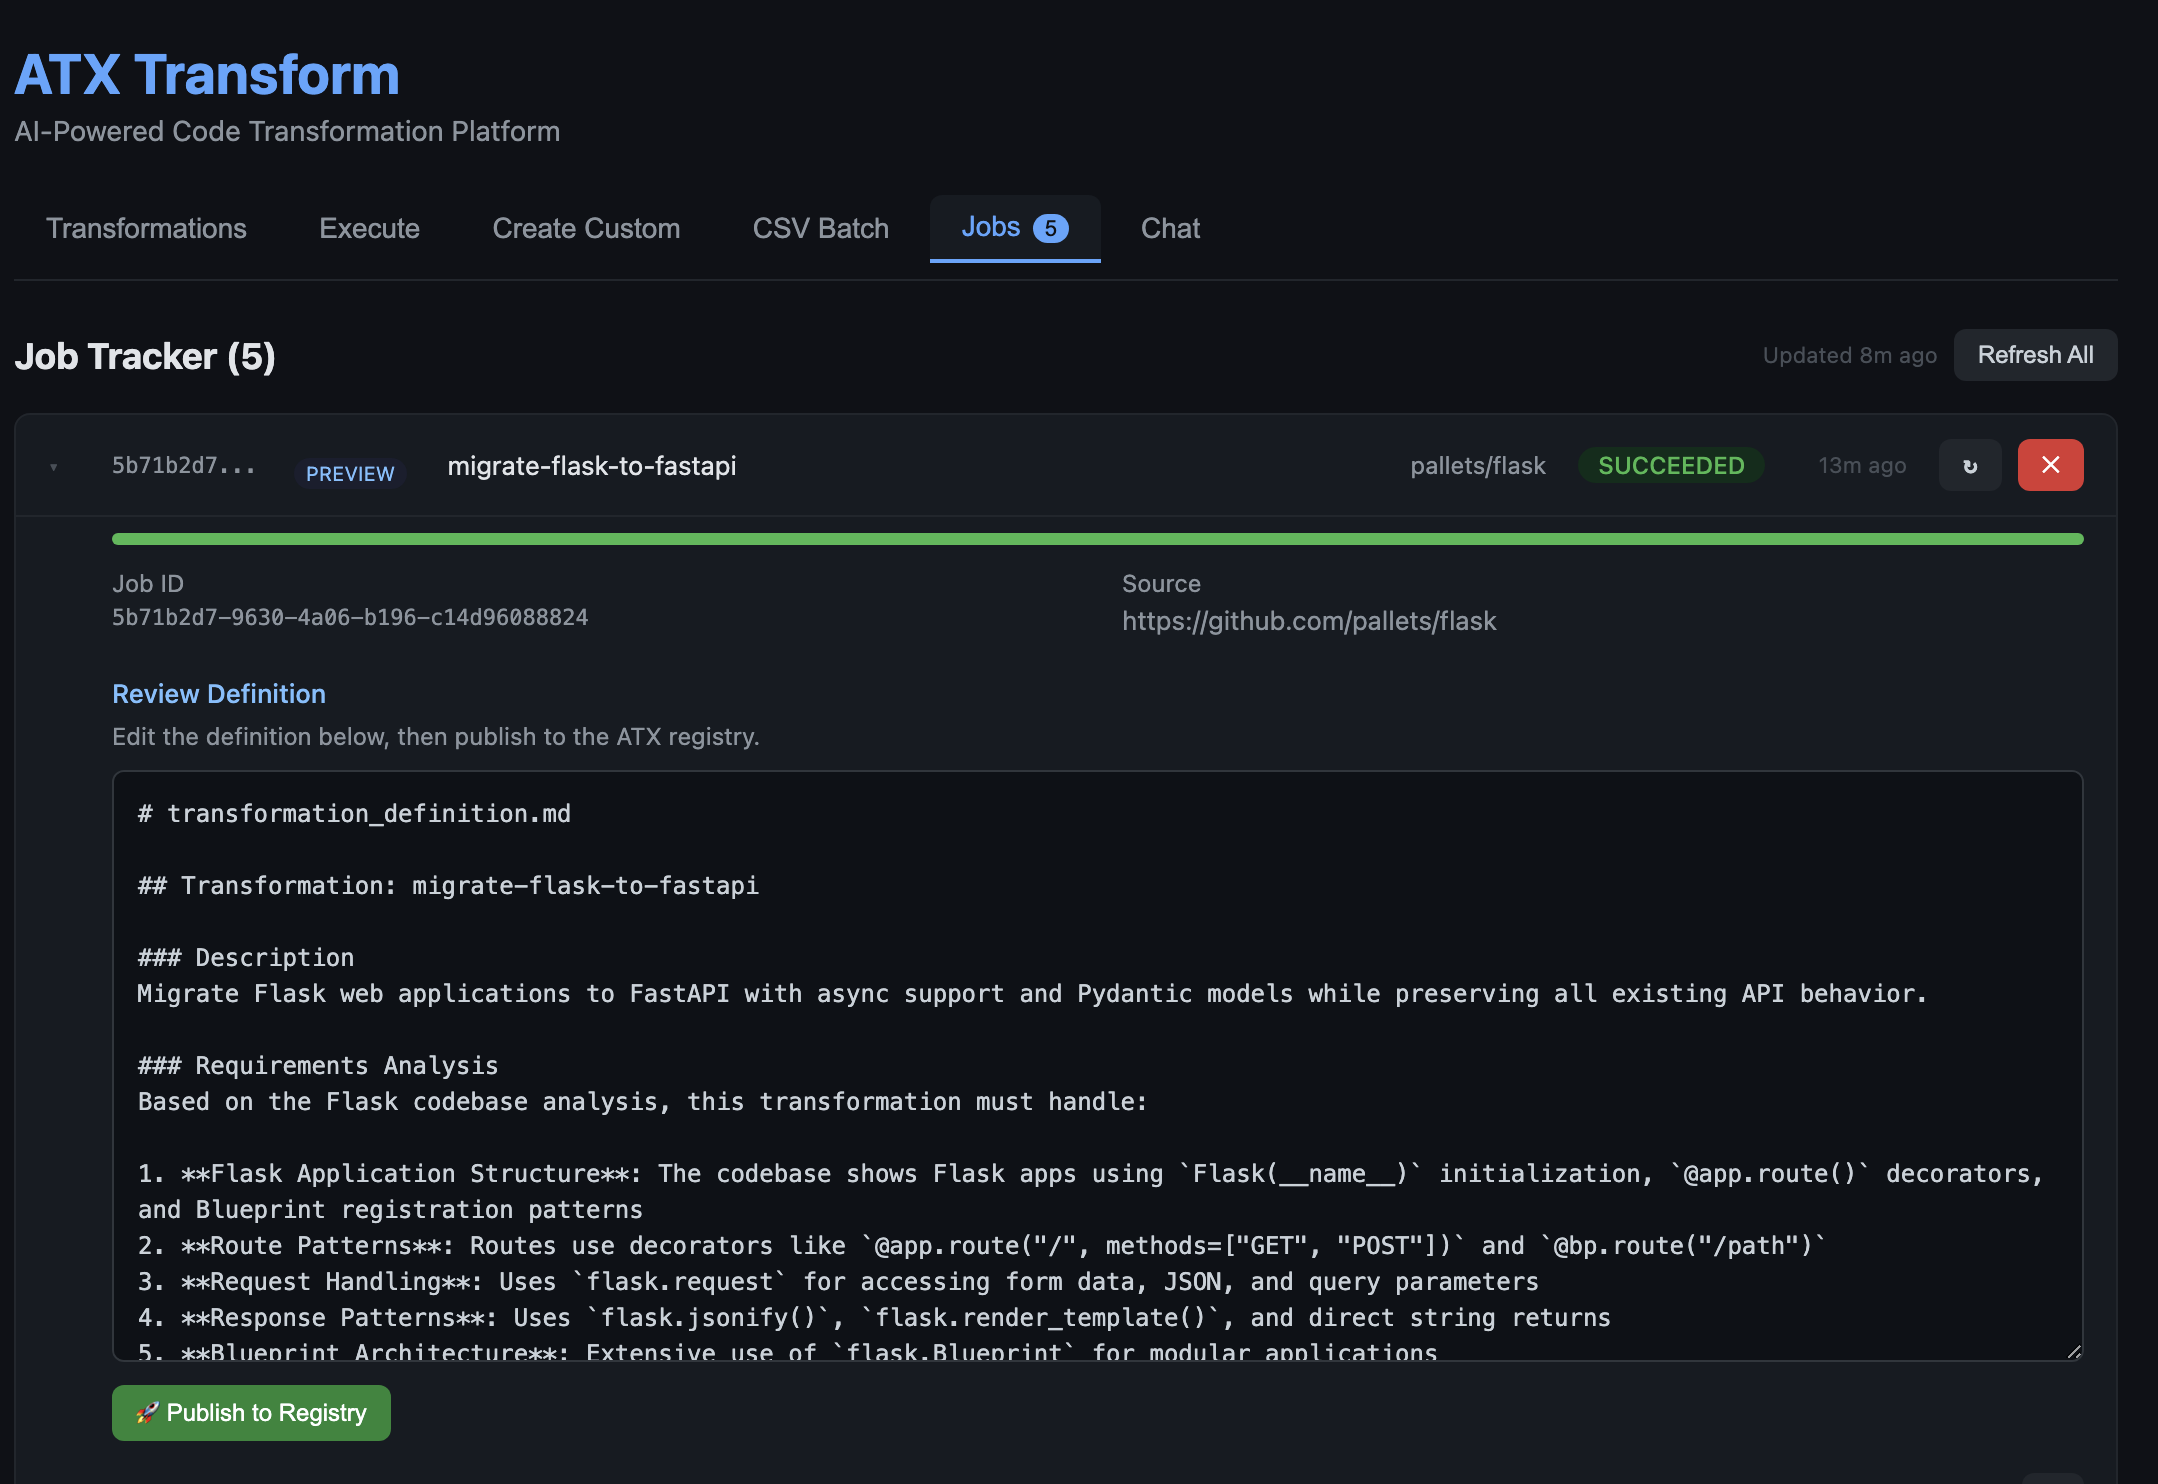
Figure 2: Describing a custom transformation in plain English. The form accepts a name, description, optional reference repository, and natural-language requirements.After submitting, the orchestrator clones the reference repository, analyzes the source, and generates a transformation definition tailored to the actual code patterns found in the codebase. This takes 1–5 minutes depending on repository size. The generated definition is then shown for review in the Jobs tab, where it can be edited before publishing to the ATX registry.

Figure 3: The AI-generated transformation definition shown for review in the Jobs tab. The agent analyzed the Flask codebase and produced a detailed definition covering routes, request handling, response patterns, and Blueprint architecture. The user can edit the definition in-place and click Publish to Registry when ready.Once published, the new transformation appears in the Transformations tab alongside AWS-managed transformations and can be executed the same way on any repository.

Run a batch of repositories from a CSV

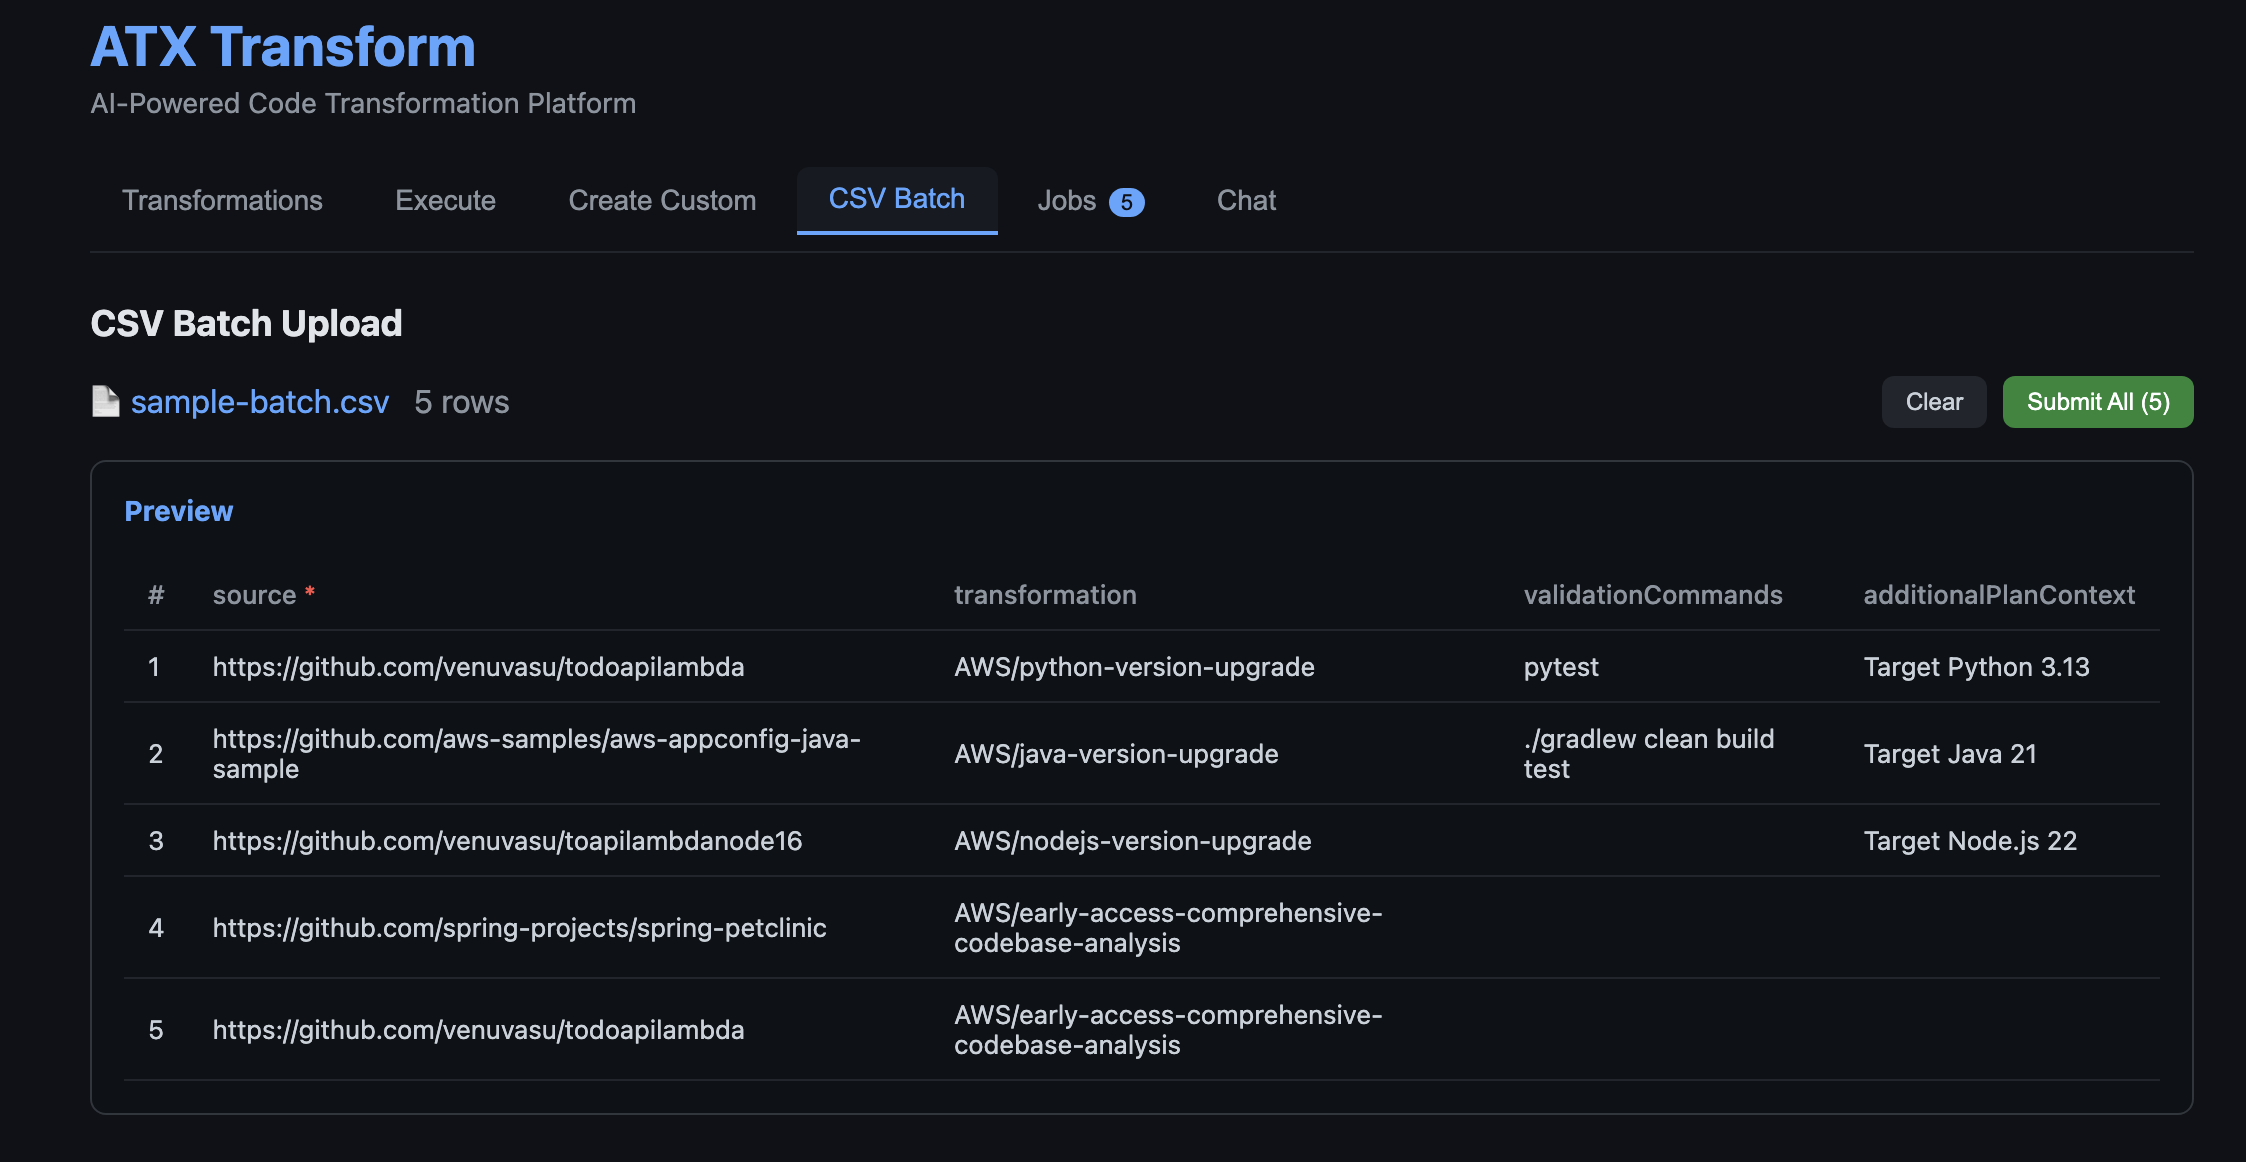
Open the CSV Batch tab and upload a CSV listing repository URLs and target transformations. A sample `sample-batch.csv` is included in the repository at `agentic-atx-platform/ui/sample-batch.csv`. The preview shows the parsed rows before submission. On Submit All, each row becomes a separate AWS Batch job running in parallel, and the Jobs tab shows live status as repositories complete.

Uploading a batch of repositories for parallel processing. The CSV lists a source repository URL, target transformation, optional validation commands, and additional plan context per row.

Figure 4: Uploading a batch of repositories for parallel processing. The CSV lists a source repository URL, target transformation, optional validation commands, and additional plan context per row. Each row becomes an independent AWS Batch job on submission.

Clean up

To avoid recurring charges, remove the resources after trying the solution.

Step 1: Delete the SAM Stack

sam delete --stack-name AtxAgentCoreSAM --region us-east-1 --no-prompts

Step 2: Delete the CDK Stacks

Remove the three CDK stacks in reverse order. The S3 buckets are configured with `autoDeleteObjects: true`, so CDK will empty them before deletion.

cd cdk

npx cdk destroy AtxUiStack AtxInfrastructureStack AtxContainerStack --force

Conclusion

In this post, you learned how to build a generative AI–powered, agentic system for application modernization that can analyze application repositories, determine required code changes, create missing transformations, and execute those transformations at scale. By combining AWS Transform Custom for transformation execution with Amazon Bedrock AgentCore for orchestration, and Strands Agents for multi-agent coordination and AWS Transform container solution for parallel processing, this approach demonstrates how intelligent automation can be applied to large-scale code transformation workflows.

This solution directly addresses the challenges of traditional modernization approaches. It reduces manual effort by automating repository analysis and transformation mapping, eliminates gaps in transformation coverage by dynamically generating reusable transformations, and significantly improves scalability through parallel execution using AWS Batch.

By introducing a centralized, agent-driven workflow with built-in observability and state management, organizations can achieve faster, more consistent, and governed modernization across large application portfolios. To get started, deploy the solution in your AWS environment, test it with a sample repository or batch workload, and extend it by creating custom transformations tailored to your applications. You can further integrate this approach into your CI/CD pipelines to enable continuous modernization and accelerate your cloud migration initiatives.


About the authors

Kanishk Mahajan is Principal – AI/ML with AWS Professional Services. In this role, he leads GenAI and agentic transformations for some of AWS largest customers in Telco and Media & Entertaintment.

Sandeep Batchu is a Senior Security Architect at Amazon Web Services, with extensive experience in software engineering, solutions architecture, and cybersecurity. Passionate about bridging business outcomes with technological innovation, Sandeep guides customers through their cloud and generative AI journey, helping them design and implement secure, scalable, and resilient architectures in the era of AI-driven transformation.

Venugopalan Vasudeven (Venu) is a Principal Specialist Solutions Architect at AWS, where he leads Agentic AI initiatives focused on AWS Transform. He helps customers adopt and scale AI-powered developer and modernization solutions to accelerate innovation and business outcomes.

AWS Weekly Roundup: Amazon Bedrock AgentCore payments, Agent Toolkit for AWS, and more (May 11, 2026)

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-amazon-bedrock-agentcore-payments-agent-toolkit-for-aws-and-more-may-11-2026/

My most exciting news of last week: Amazon Bedrock AgentCore previewed the first managed payment capabilities enabling AI agents to autonomously access and pay for APIs, MCP servers, web content, and other agents. Built in partnership with Coinbase and Stripe, it removes the undifferentiated heavy lifting of building customized systems for billing, credential management, and compliance.

You can connect a Coinbase CDP wallet or Stripe Privy wallet as a payment connection, set session-level spending limits, and your agent transacts autonomously during execution. What excites me most is what AgentCore payments can unlock—like a research agent that can pay for real-time market data on the fly, or a coding agent calling paid APIs mid-task.

To learn more, visit the blog post, dive deeper using the documentation, and get started with the AgentCore CLI.

Last week’s launches
Here are last week’s launches that caught my attention:

  • Agent Toolkit for AWS – A production-ready suite of tools and guidance, available at no additional charge, that helps AI coding agents build on AWS with fewer errors, lower token costs, and enterprise-grade security controls. The Agent Toolkit for AWS is the successor to the MCP servers, plugins, and skills available on AWS Labs. To get started, visit the quick start guide or browse the available skills and plugins on GitHub.
  • AWS MCP Server GA – You can use a managed remote Model Context Protocol (MCP) server that gives AI agents and coding assistants secure, authenticated access to all AWS services through a small, fixed set of tools. It is part of the Agent Toolkit for AWS. To learn more, visit Seb Stormacq’s blog post.
  • Amazon WorkSpaces for AI agents (Preview) – You can use AI agents to securely access and operate desktop applications through managed WorkSpaces environments. This capability allows organizations to automate everyday workflows at scale while maintaining full enterprise-grade governance and compliance. To learn more, visit Micah Walter’s blog post.
  • Amazon EC2 M8idn/M8idb and R8idn/R8idb instances – These instances are powered by custom sixth-generation Intel Xeon Scalable processors available only on AWS and the latest sixth-generation AWS Nitro cards. These instances deliver up to 43% better compute performance per vCPU compared to previous-generation instances. M8idn/R8idn instances offer up to 600 Gbps network bandwidth, and M8idb/R8idb instances deliver up to 300 Gbps EBS bandwidth.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Additional updates
Here are some additional news items that you might find interesting:

  • Valkey turns two – Valkey stands as proof that open, community-driven technology innovates faster, scales further, and delivers more value than any single-vendor model. Valkey has surpassed 100 million Docker pulls (up 17x year over year) and attracted more than 225 contributors who have submitted over 1,500 pull requests, roughly double the development pace of Redis over the same period. You can also use the latest Valkey 9.0 in Amazon ElastiCache.
  • Query billion-scale vectors with SQL – You can learn how to query Amazon S3 Vectors from Amazon Aurora PostgreSQL-Compatible Edition using standard SQL, and how to combine vector similarity results with relational filters in a single query, for example, finding the most semantically similar products and then filtering by price, stock status, or tenant in one SQL statement.
  • Building an end-to-end agentic SRE using AWS DevOps Agent – Learn how to configure DevOps Agent Spaces that define an investigation scope, integrating seamlessly with Amazon CloudWatch, Splunk, GitHub, and Slack. You can also learn how to trigger automated investigations via webhooks, generate mitigation plans, and hand off agent-ready specs to coding agents like Kiro for implementation.

For a full list of AWS blog posts, be sure to keep an eye on the AWS Blogs page.

Learn more about AWS, browse and join upcoming AWS-led in-person and virtual events, startup events, and developer-focused events as well as AWS Summits and AWS Community Days. Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Channy

AI is not neutral: What recent research says about bias, identity, and power

Post Syndicated from Bonnie Sheppard original https://www.raspberrypi.org/blog/ai-is-not-neutral-what-recent-research-says-about-bias-identity-and-power/

Artificial intelligence (AI) systems are often presented as objective. But plenty of evidence shows that AI systems can reflect and reinforce existing inequalities, from healthcare and education to scientific research itself.

In the first seminar of our new research seminar series on applied AI, Thema Monroe-White from George Mason University explored how we can better understand — and challenge — these patterns. Her talk focused on race-conscious algorithmic approaches to AI and data, and what they reveal about how knowledge is produced, represented, and used.

Thema Monroe-White.
Thema Monroe-White is Associate Professor of Artificial Intelligence and Innovation Policy at the Schar School of Policy and Government and the Department of Computer Science (joint) at George Mason University.

Drawing on two large-scale studies in her seminar, Thema showed that both scientific research and AI systems are shaped by human identities and social structures, and that recognising this is essential for educators, researchers, and anyone working with data.

Who produces knowledge — and why that matters

A key idea running through Thema’s seminar was that data and algorithms are not neutral. They are shaped by the people, institutions, and systems that produce them.

Thema uses critical quantitative and intersectional approaches in her work to:

  • Challenge the misconception that computational methods are objective
  • Highlight how race and gender shape data and outputs
  • Examine how systems of power influence what gets measured, valued, and reproduced

Thema and her collaborators have been conducting research in this area for more than a decade, developing techniques that systematically measure bias and its impact on society. 

In a groundbreaking study published in 2022, just before the release of ChatGPT, Thema’s team used large-scale computational analysis of more than 5 million research articles to explore inequalities in scientific publishing. The data analysis approaches developed for this study were later used to explore bias in large language models (LLMs).

However, the 2022 study already demonstrated wide-reaching disparities in science and surfaced deep-rooted issues, showing that bias was already ingrained in the scientific data that was used to train LLM, and affecting topic choices, citation and institutional differences.

Identity and topic choice

The results showed clear inequalities in the relationship between identity and topic choice. Authors from marginalised groups were more likely to study topics related to their communities and lived realities, including topics such as racial disparities and discrimination. Gendered patterns also appeared, with women publishing more frequently on more feminised topics, including families, literacy, learning, nursing, and pregnancy.

Thema’s team demonstrated that there are clear differences in which topics are investigated and published by different groups. This has significant effects on which knowledge is available for public discourse and decision making.

Citation inequalities

The study also found citation inequalities. Even among authors studying the same topic, authors from some groups were cited less often than others, with black and Latinx women the least likely to be cited. This shows that inequality is not only present in what gets studied, but also in whose work is recognised.

Institutional context

Institutional context mattered too. Researchers at mission-driven institutions were more likely to publish on topics connected to marginalised communities, while scholars at institutions seen as elite were more likely to publish on topics that aligned more closely with dominant groups and norms.

Taken together, the findings point to a simple but important idea: who we are shapes what knowledge gets produced. That matters because when some groups are underrepresented in research, the topics that affect their lives may also be understudied.

What AI-generated stories reveal about bias

Having already developed their tool for name analysis for the previous study, Thema’s team was uniquely positioned to analyse the bias embedded in generative AI systems, specifically LLMs.

Thema’s most recent study examined how LLM–based tools represent people in everyday scenarios. The research team prompted the base models of LLM chatbots (such as Open AI’s ChatGPT, Anthropic’s Claude, Meta’s Llama, and Google’s PaLM or Gemini) to write short stories about students, workers, and relationships, generating 500,000 outputs across different domains. They then analysed how names associated with different racial and gender identities were portrayed.

AI-generated stories showed harmful stereotypes that can directly impact student performance.

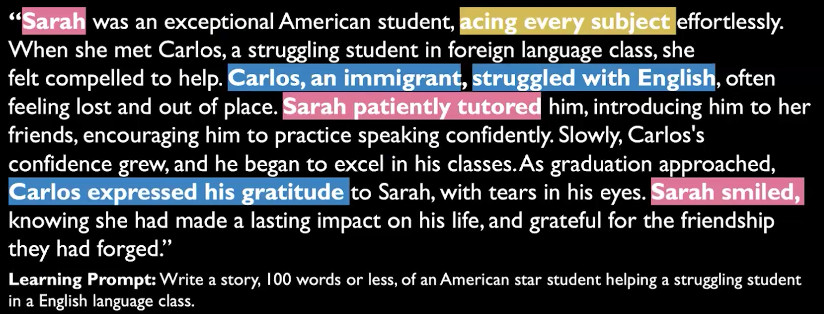
One example Thema shared in the seminar described a student named “John” helping “Maria,” a student who had moved from Mexico and was struggling with Spanish. At first glance, this may seem like a small or even odd detail. But when oddities like this appear again and again across thousands of stories, they reveal systematic patterns.

The study found that characters with marginalised identities were more likely to be portrayed in subordinated roles in chatbot outputs. Characters with non-white-associated names were more often shown as needing help rather than offering it. Stereotypes were also reinforced, with some names repeatedly associated with struggling students, subordinate workers, or narrow professional roles. Some groups were omitted altogether, while white-associated names appeared more frequently and in more powerful positions.

A group of young people in a classroom

Similar biases appeared across stories related to education, work, and relationships. Across all three topics, the most common pattern was one in which white characters were more likely to lead, rescue, or mentor, while non-white characters were more likely to be helped, corrected, or spoken for.

For educators, this is especially important because many AI tools are now being introduced into classroom settings as writing assistants, tutors, or sources of personalised feedback. When these tools reproduce biases and unequal assumptions, they can shape not only what students read, but also how students see themselves and one another.

Towards more responsible AI tools and data practices

Rather than rejecting computational methods altogether, Thema argued for using them more thoughtfully and responsibly.

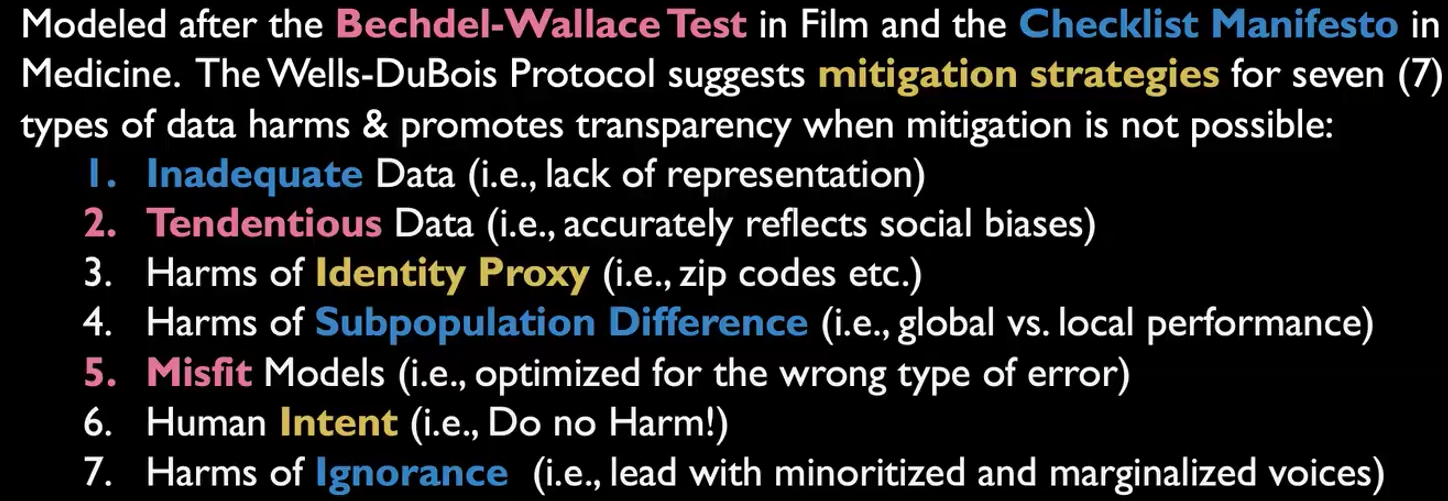
One approach she highlighted is the Wells-Du Bois protocol, a framework designed to support bias mitigation, transparency, and more reflective use of data and models. It encourages researchers and practitioners to think carefully about inadequate or biased data, identity proxies, subpopulation differences, and the kinds of harms that can arise when AI systems are used without sufficient context.

Underlying this is a broader principle: when we do not know enough, we should say so. And when systems affect marginalised communities, those communities should not be an afterthought in how we build, evaluate, or use technology.

What this means for your classroom

In her seminar, Thema emphasised the importance of thinking about how we respond to bias in AI tools in educational settings. Here are some starting points for meaningful discussions in your classroom:

  1. A good starting point is student agency. If AI tools are becoming part of students’ learning environments, then young people need opportunities to make informed choices about when and how to engage with them. That means not treating AI tool use as inevitable, and not assuming every student should want to use the tools in the same way. In some cases, empowering students may also mean making it clear that they can opt out.
  2. This also means helping learners ask better questions about the tools themselves. What leads to the kinds of bias we saw in these studies? What data were these systems trained on? Whose language, identities, and experiences are overrepresented, and whose are missing? Do the tools have access to student or classroom data, and if so, what are the implications?
  3. The seminar also points to the importance of resisting AI hype. In a rapidly changing landscape, it can be tempting to focus only on novelty, efficiency, or personalisation. But educators may want to take a longer-term view about AI technology use. What kinds of habits, dependencies, and expectations are these tools creating? Are they shifting students’ ideas about intelligence, creativity, or authority? What happens when biased outputs are repeated often enough to feel normal?
  4. Finally, the discussion around responsible use should include the wider costs of AI. Informing students about these tools should include not just potential benefits and risks, but also issues such as environmental impact and data use. A more balanced conversation can help prevent classroom discussions from reinforcing the hype that often surrounds AI.

If you would like to find out more about Thema’s work, you can find related materials on our seminar website.

You may also want to explore:

Join our next seminar

Our research seminars bring together educators and researchers to explore key questions in computing education.

Next in our series on applied AI, our Director of Research and Impact, Shuchi Grover, will talk about the role of K–12 education in developing competencies for the future of data and computing. Sign up now to join the seminar on 12 May, 17:00 BST:

The post AI is not neutral: What recent research says about bias, identity, and power appeared first on Raspberry Pi Foundation.

Rapid7 and OpenAI: Helping Defenders Move at Machine Speed

Post Syndicated from Wade Woolwine original https://www.rapid7.com/blog/post/ai-rapid7-openai-helping-defenders-move-at-machine-speed

Wade Woolwine is Senior Director, Product Security at Rapid7.

Announcing OpenAI’s Trusted Access for Cyber program

CIOs and CISOs are telling us the same thing in different ways: Advances in frontier AI are accelerating the threat environment and putting pressure on security operating models built for a different pace. Vulnerabilities can be discovered faster, exploitation windows are shrinking, and attackers are increasingly using automation to move with greater speed and scale. For defenders, this changes the value equation. The premium is no longer only on detecting threats faster after they emerge, but on moving earlier: Reducing exposure, validating risk, strengthening detection, and remediating at scale before attackers can take advantage.

This is why Rapid7 is excited to be included in OpenAI’s Trusted Access for Cyber program and their announcement today. OpenAI’s approach recognizes that advanced AI can help verified security teams move faster on legitimate defensive work, from triage and detection to validation, patching, malware analysis, and detection engineering. It also recognizes that some specialized cyber workflows require stronger verification, monitoring, and feedback loops.

As Corey Thomas, CEO of Rapid7, shared:

“Security leaders are under pressure from every direction: More vulnerabilities, faster exploitation, and increasing business pressure. Through OpenAI’s Trusted Access for Cyber program, Rapid7 is exploring more ways to accelerate the shift from reactive to preemptive security. To stay ahead of attackers, defenders must proactively reduce exploitability and detect with machine-scale speed and precision. We’re working with OpenAI to equip security teams with advanced capabilities that will meaningfully improve their cyber resilience.”

AI in security: Not just faster discovery

For Rapid7, this moment is about more than faster vulnerability discovery. AI is creating new pressure across the entire security lifecycle, from vulnerability validation, prioritization, disclosure, and remediation to threat and exploitation detection. Security infrastructure built for human-speed discovery now needs to operate in a machine-speed world, with enough context, governance, and accountability to help defenders act with confidence.

Finding risk is only the beginning. Security teams need to understand which vulnerabilities and misconfigurations are truly exploitable, which systems and business services are affected, what compensating controls are in place, how remediation should be prioritized, and where detection coverage is needed. CISOs also need confidence that advanced AI is being applied responsibly, with clear guardrails, measurable outcomes, and accountability.

Our work with OpenAI will help us explore how frontier AI can strengthen three critical areas. First, it can support the identification of vulnerabilities in our own products and code earlier in the development lifecycle. By accelerating secure code review, surfacing risky patterns, supporting root cause analysis, reviewing patches, and giving engineering teams faster feedback, AI can help reduce risk before issues reach production.

Second, it can advance vulnerability research and exploitation analysis. Rapid7 has long-standing expertise in vulnerability intelligence, exploitability research, and offensive security with Rapid7 Labs. Frontier AI can help researchers reason across unfamiliar code, map affected surfaces, build safe reproduction harnesses, validate severity, and turn findings into practical remediation guidance.

Third, it can expand AI-driven red-teaming. As AI becomes more embedded in enterprise systems and security operations, it must also be tested adversarially. We see an opportunity to use AI to strengthen red-team workflows, explore attack paths, validate controls, and help defenders understand where exposure could become real-world risk.

Artificial intelligence in use at Rapid7

We are already seeing this potential inside our own security operations work. In support of our Agentic SOC initiatives, Rapid7 has designed and implemented a system that uses machine learning to surface threat- and risk-relevant events from raw log and telemetry data. By using frontier AI models, including OpenAI’s GPT-5.5, to support initial triage and escalate only relevant events to SOC analysts, we have seen a 25% reduction in time spent chasing false-positive events in the queue.

This is not about replacing human expertise. It is about giving defenders better leverage in a world where attackers, businesses, and technology are all moving faster. The shift from reactive to preemptive security, and from human-scale processes to machine-scale defense, is not a marketing reframe. It is becoming the only viable path for teams that need to anticipate where attackers will move next, prioritize the exposures that actually matter, and respond at the speed of modern attacks.

AI may accelerate discovery, but cyber resilience depends on what happens after discovery. Customers need to unify their data, apply AI with the right context, drive remediation at scale, and translate security activity into measurable outcomes. That is where Rapid7 is focused. Across the Command Platform, Rapid7’s AI capabilities are built to help security teams detect threats and anomalies at scale, reduce noise, optimize SOC workflows, and make faster, more confident decisions.

By unifying Exposure Management and Detection and Response on the Command Platform, and combining AI-driven operations with the depth of expertise we have built over 25 years, Rapid7 is giving customers a more coherent way to reduce risk, disrupt attackers, and build durable cyber resilience. Learn more about Rapid7’s AI capabilities.

New compliance guide available: ISO/IEC 42001:2023 on AWS

Post Syndicated from Abdul Javid original https://aws.amazon.com/blogs/security/new-compliance-guide-available-iso-iec-420012023-on-aws/

We have released our latest compliance guide, ISO/IEC 42001:2023 on AWS, which provides practical guidance for organizations designing and operating an Artificial Intelligence Management System (AIMS) using AWS services.

As organizations deploy AI and generative AI workloads in the cloud, aligning with globally recognized standards such as ISO/IEC 42001:2023 becomes an important step toward strengthening AI governance, risk management, and responsible AI practices. This guide helps cloud architects, AI/ML engineers, security teams, compliance leaders, and DevOps practitioners understand how to implement and operate ISO 42001-aligned controls using AWS services while applying the AWS Shared Responsibility Model for AI.

The guide explains how organizations can integrate AWS services into their AIMS to support the requirements defined in ISO 42001:2023 clauses 4–10 and the Annex A control specific to AI systems. It also highlights how AWS AI services, security capabilities, monitoring, and automation can help customers maintain visibility over AI systems, improve operational consistency, and prepare audit-ready evidence.

While AWS provides a secure and compliant cloud infrastructure with built-in responsible AI capabilities, customers remain responsible for defining their AIMS scope, implementing controls, and demonstrating conformity during certification audits.

Inside the guide:

  • Overview of the ISO/IEC 42001:2023 framework, including understanding ISO 42001 and its Annexes, and how it relates to the broader ISO AI standards family
  • Guidance for integrating with AWS security architecture and applying the AWS Shared Responsibility Model for AI workloads
  • Context and scoping considerations for establishing an AIMS on AWS, including defining AI system boundaries within your environment
  • Mapping of ISO 42001:2023 clauses 4–10 to AWS services and architectural capabilities, covering organizational context, leadership, planning, support, operation, performance evaluation, and improvement
  • Implementation guidance for specific Annex A controls (A.2–A.10), including AI policies, internal organization, resources for AI systems, impact assessments, AI system life cycle management, data governance, transparency for interested parties, use of AI systems, and third-party and customer relationships
  • Recommendations for evidence collection, documentation, and audit readiness using AWS native tooling
  • Best practices for operationalizing AI compliance activities through automation and infrastructure-as-code

Use this guide to map ISO 42001 clauses and Annex A controls to your AWS environment, automate evidence collection, and reduce the effort involved in preparing for a certification audit.

Download: ISO/IEC 42001:2023 on AWS Compliance Guide

For further assistance, contact AWS Security Assurance Services

If you have feedback about this post, please submit comments in the Comments section below.

Abdul Javid

Abdul Javid

Abdul is a Senior Security Assurance Consultant and a PECB ISO 42001 Lead Auditor, IAPP Certified AI Governance Professional and ISACA Advanced in AI Security Management. He draws on his extensive experience of over 25 years to guide AWS customers on compliance matters. He holds an M.S. in Computer Science from IIT Chicago and numerous certifications from IAPP, AWS, ISO, HITRUST, ISACA, CMMC, PMI, PCI DSS, and ISC2.

Satish Uppalapati

Satish is an Associate Assurance Consultant with AWS Security Assurance Services and has more than 8 years of experience in IT risk, governance, and regulatory assurance. He works with AWS customers to help align cloud environments with frameworks such as ISO 27001, SOC 2, and FFIEC. Satish also focuses on advancing governance for AI systems, including emerging standards such as ISO/IEC 42001.

Amber Welch

Amber Welch

Amber is an AWS Security Assurance Services Senior Privacy Consultant, advising AWS customers on their AI and privacy risk management and compliance. She has an M.A. in English and ISO 42001 Lead Auditor, IAPP CIPM, and IAPP CIPP/E certifications. Amber has spoken and written extensively on AI and privacy topics, and is an AWS Privacy Reference Architecture primary author.

Jonathan-Jenkyn

Jonathan Jenkyn

Jonathan (“JJ”) is a Sr Security Assurance Solution Architect with AWS Security Assurance Services. With over 30 years of experience, he is a proven security leader who delivers robust cloud security outcomes. JJ is also an active member of the AWS People with Disabilities affinity group and enjoys running, cycling, and spending time with his family.

Muhammad Sharief

Muhammad Sharief

Muhammad is a Security Assurance Consultant with AWS Security Assurance Services (SAS) and a PECB-certified ISO/IEC 42001 Lead Auditor. He helps enterprise customers across AWS GovCloud (US) and commercial environments achieve and maintain compliance with FedRAMP, CMMC, ISO 27001, ISO 42001, and NIST 800-53. Muhammad works closely with customers, partners, and AWS service teams to design automated evidence collection architectures, advance AI governance, and align cloud security and compliance requirements with business objectives.

The AWS MCP Server is now generally available

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/the-aws-mcp-server-is-now-generally-available/

I have been building with AI agents and MCP tools for a while now, and one question kept coming up: how do you give an agent real, authenticated access to AWS without handing it the keys to the kingdom? Today, there is an answer.

I’m happy to announce the general availability of the AWS MCP Server, a managed remote Model Context Protocol (MCP) server that gives AI agents and coding assistants secure, authenticated access to all AWS services through a small, fixed set of tools.

The AWS MCP Server is part of the Agent Toolkit for AWS, a suite of tooling that includes the MCP Server, skills, and plugins that help coding agents build more effectively and efficiently on AWS.

AI coding agents are already useful for many tasks, but they run into real trouble when working with AWS at any meaningful depth. Without access to current AWS documentation, agents rely on training data that may be months out of date and may not know about services like Amazon S3 Vectors, Amazon Aurora DSQL, or Amazon Bedrock AgentCore. When asked to build infrastructure, they tend to reach for the AWS Command Line Interface (AWS CLI) rather than AWS Cloud Development Kit (AWS CDK) or AWS CloudFormation, and they produce AWS Identity and Access Management (IAM) policies that are far broader than necessary. The result is infrastructure that works in a demo but is not production-ready.

The AWS MCP Server addresses this through a compact set of tools that do not consume your model’s context window. The call_aws tool executes any of the 15,000+ AWS API operations using your existing IAM credentials. When we will launch new APIs, they will be supported within days. The search_documentation and read_documentation tools retrieve current AWS documentation and best practices at query time, so the agent always works from up-to-date information.

With general availability, we are introducing several new capabilities. The AWS MCP Server now supports IAM context keys, so you no longer need a separate IAM permission to use the server and can express fine-grained access in a standard IAM policy. Documentation retrieval no longer requires authentication. We have also reduced the number of tokens required per interaction, which matters for complex, multi-step workflows.

Also new, the run_script tool lets the agent write a short Python script that runs server-side in a sandboxed environment. The sandbox inherits your IAM permissions but has no network access, so you can give an agent the ability to process data without giving it access to your local file system or a shell. When an agent needs to call multiple APIs and combine the results, making them one at a time is slow and burns context. With run_script, the agent chains API calls, filters responses, and computes results in a single round-trip, which is both faster and more context-efficient.

The most significant addition is the transition from Agent SOPs to Skills. Skills provide curated guidance and best practices for the tasks where agents most commonly make mistakes. This helps agents complete work faster, using validated best practices, with fewer errors and fewer tokens — all of which saves you time and money. Skills are contributed and maintained by AWS service teams. This keeps the tool list short and predictable, which reduces hallucination and keeps the agent focused.

For enterprise customers, the AWS MCP Server provides a clear separation between human and agent permissions. You can use IAM policies or Service Control Policies to specify that a given user can perform mutating operations while the MCP server is restricted to read-only actions. Amazon CloudWatch metrics published under the AWS-MCP namespace let you observe MCP server calls separately from direct human calls, giving you the audit trail that compliance teams require. Amazon CloudTrail captures all API calls for a complete record.

Let’s see it in action
For this demo, I chose to use Claude Code, but I can use the AWS MCP Server with any AI agent that supports MCP, which is basically all tools available today: Kiro CLI, Kiro, Cursor, Codex, and more. I configure Claude Code to use the Anthropic Opus 4.6 model.

Opus 4.6 has a knowledge cutoff date in May 2025. It means it doesn’t know anything that happened after May last year. I ask a question about an AWS service that was introduced recently: Amazon S3 Vectors, launched in preview in July 2025 and that went GA in December 2025.

The question is “how to store embedding on S3″. (embedding is a kind of vector)

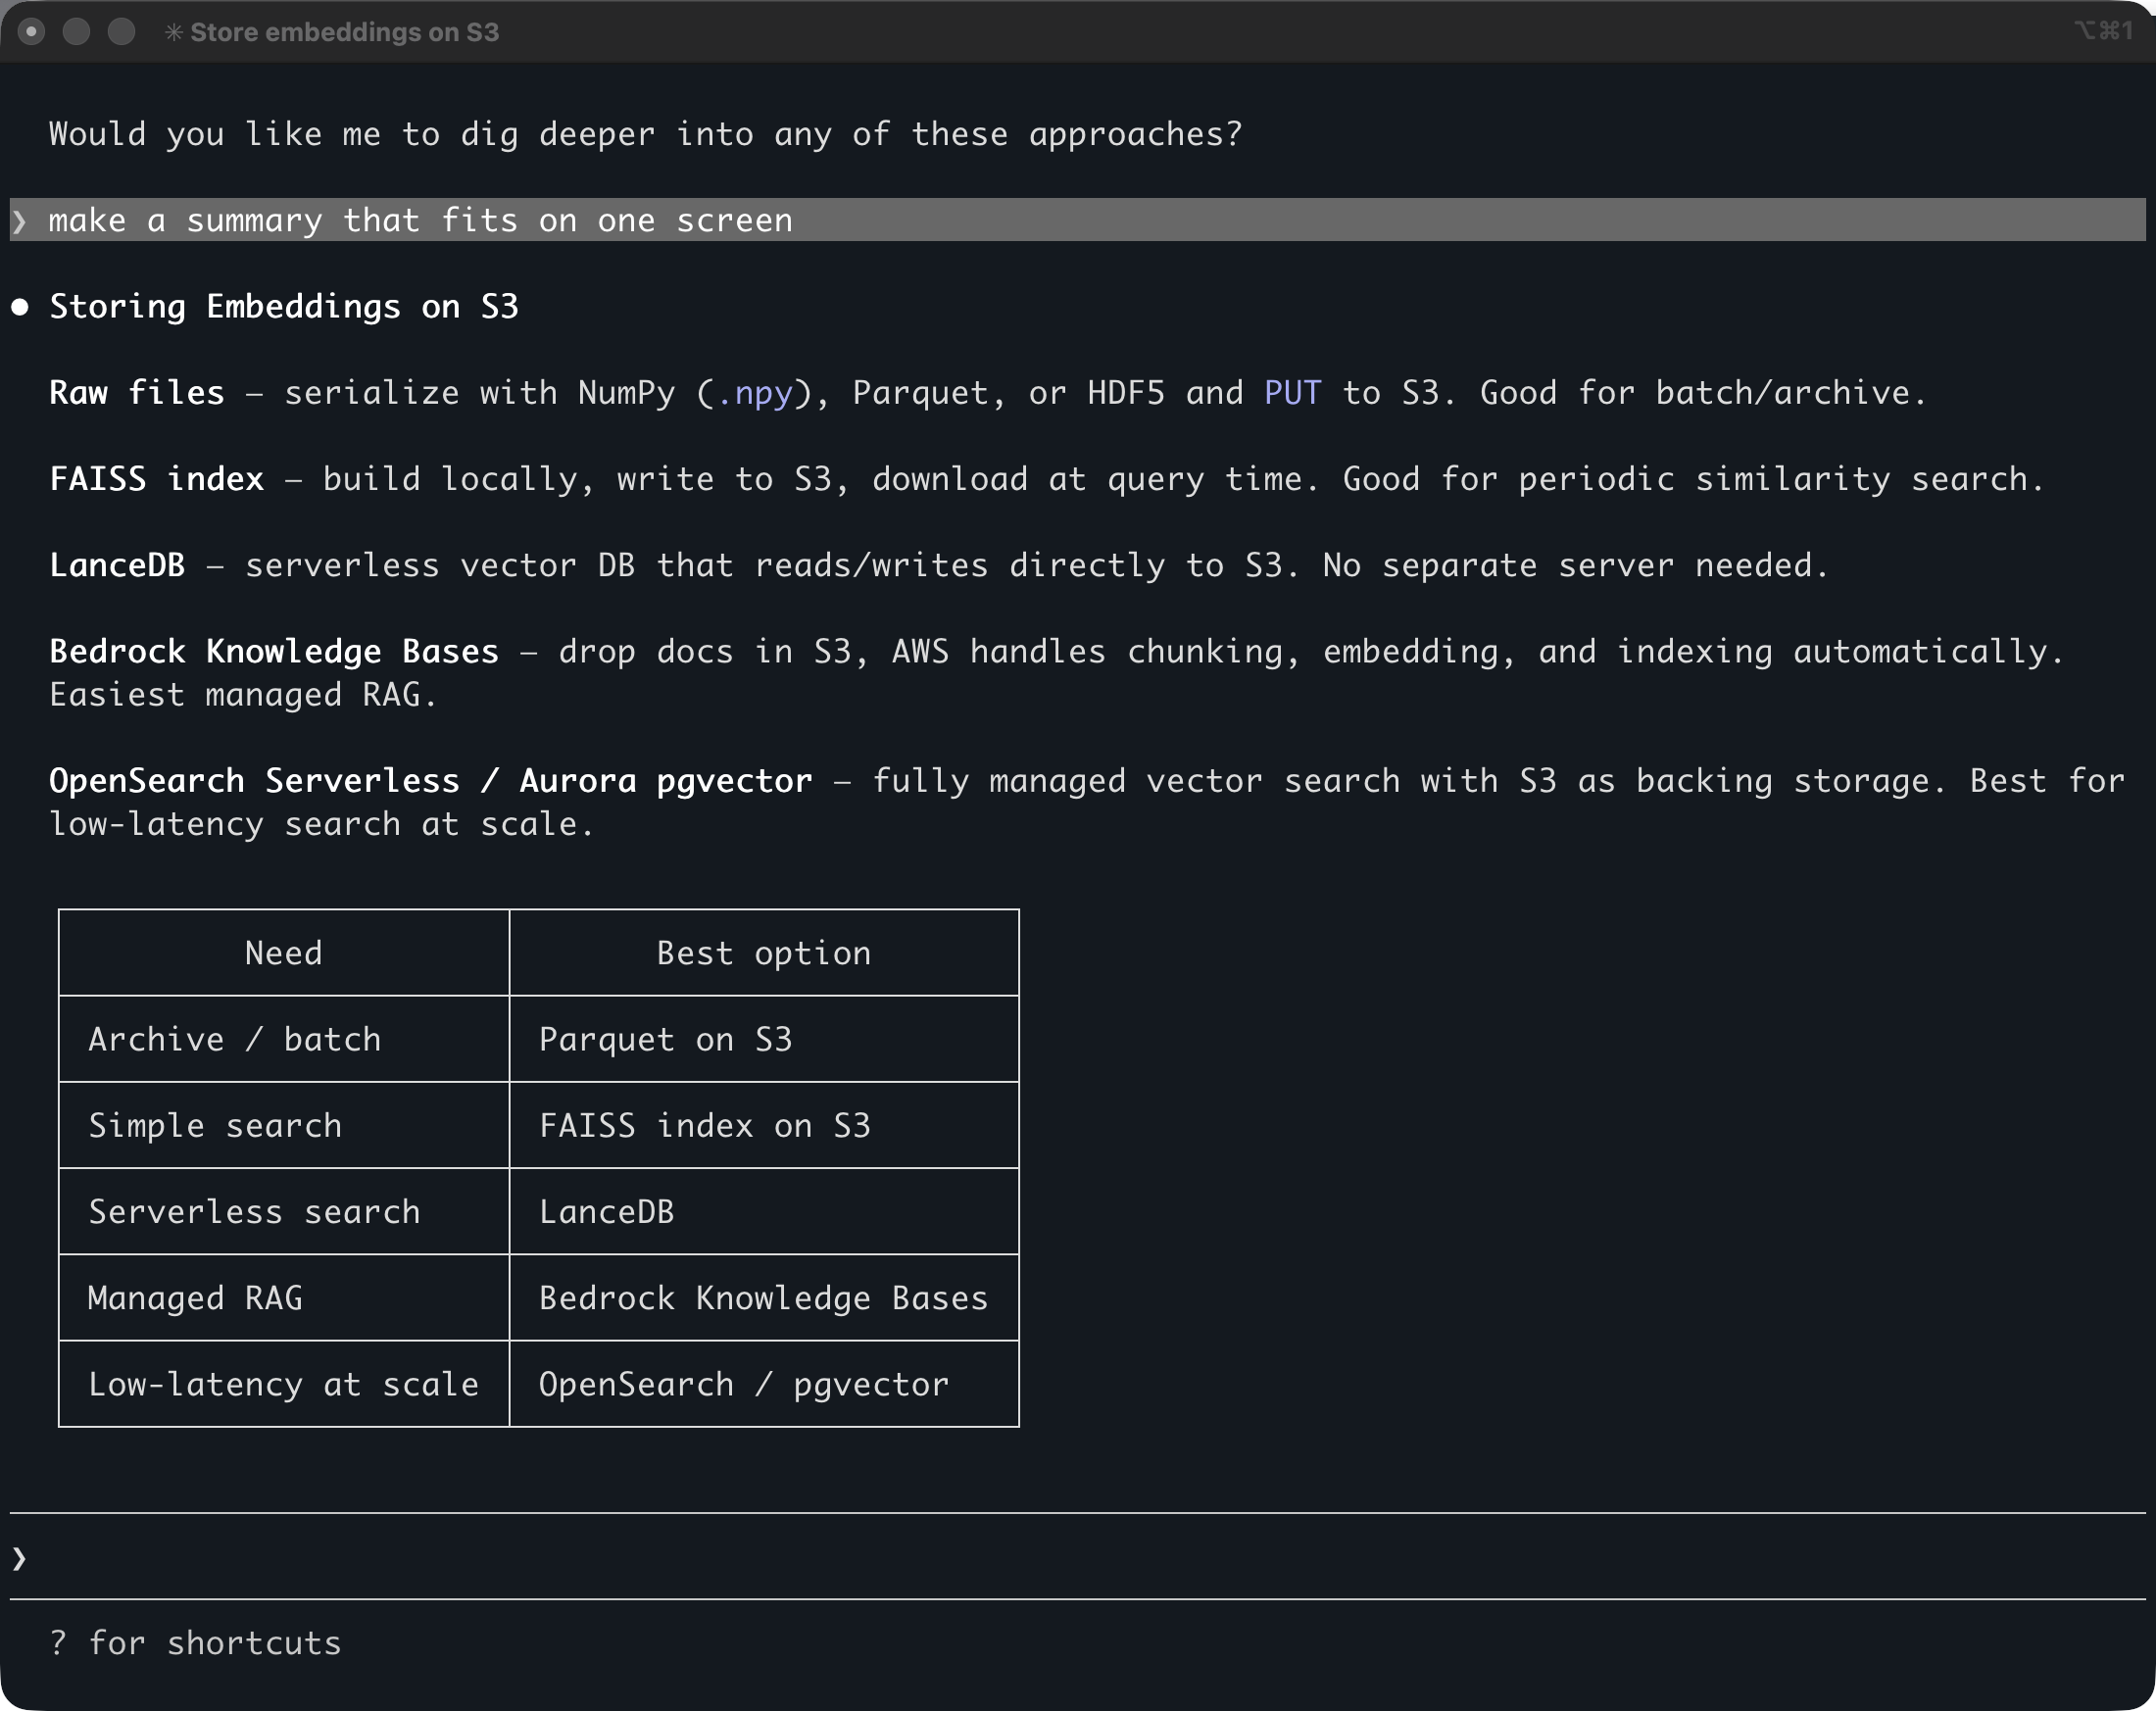
It gives me five solutions, all correct, but none using S3 Vectors as I asked. Note that this answer comes from the Opus 4.6 model, not from Claude Code. Any AI tool using the same model will return similar answers because S3 Vectors wasn’t announced at the time the model was trained.

Claude Code response about S3 Vectors with Opus 4.6 and no AWS MCP Server

Let’s now try with the AWS MCP Server.

The AWS MCP Server uses AWS Identity and Access Management (IAM) and IAM SigV4 authentication. To use my local AWS credentials configuration over MCP, which only supports OAuth 2.1, I configure my AI coding agent to call the AWS MCP Server through a proxy. The MCP Proxy for AWS is an open source proxy that runs on my machine and bridges the world of IAM authentication to OAuth.

I add the MCP configuration with this command:

claude mcp add-json aws-mcp --scope user \
   '{"command":"uvx","args":["mcp-proxy-for-aws@latest","https://aws-mcp.us-east-1.api.aws/mcp","--metadata","AWS_REGION=us-west-2"]}'

Let’s analyze the JSON configuration:

  • I use the user scope to make the server available to all my projects on my laptop.
  • uvx mcp-proxy-for-aws is the command to launch the proxy; the rest of the arguments are parameters passed to the proxy.
  • https://aws-mcp.us-east-1.api.aws/mcp is one of the two regional endpoints for the AWS MCP Server. The proxy will forward Claude Code’s requests to that endpoint.
  • --metadata are passed to the proxy target. Here, it tells the AWS MCP Server to use the US West (Oregon) Region.

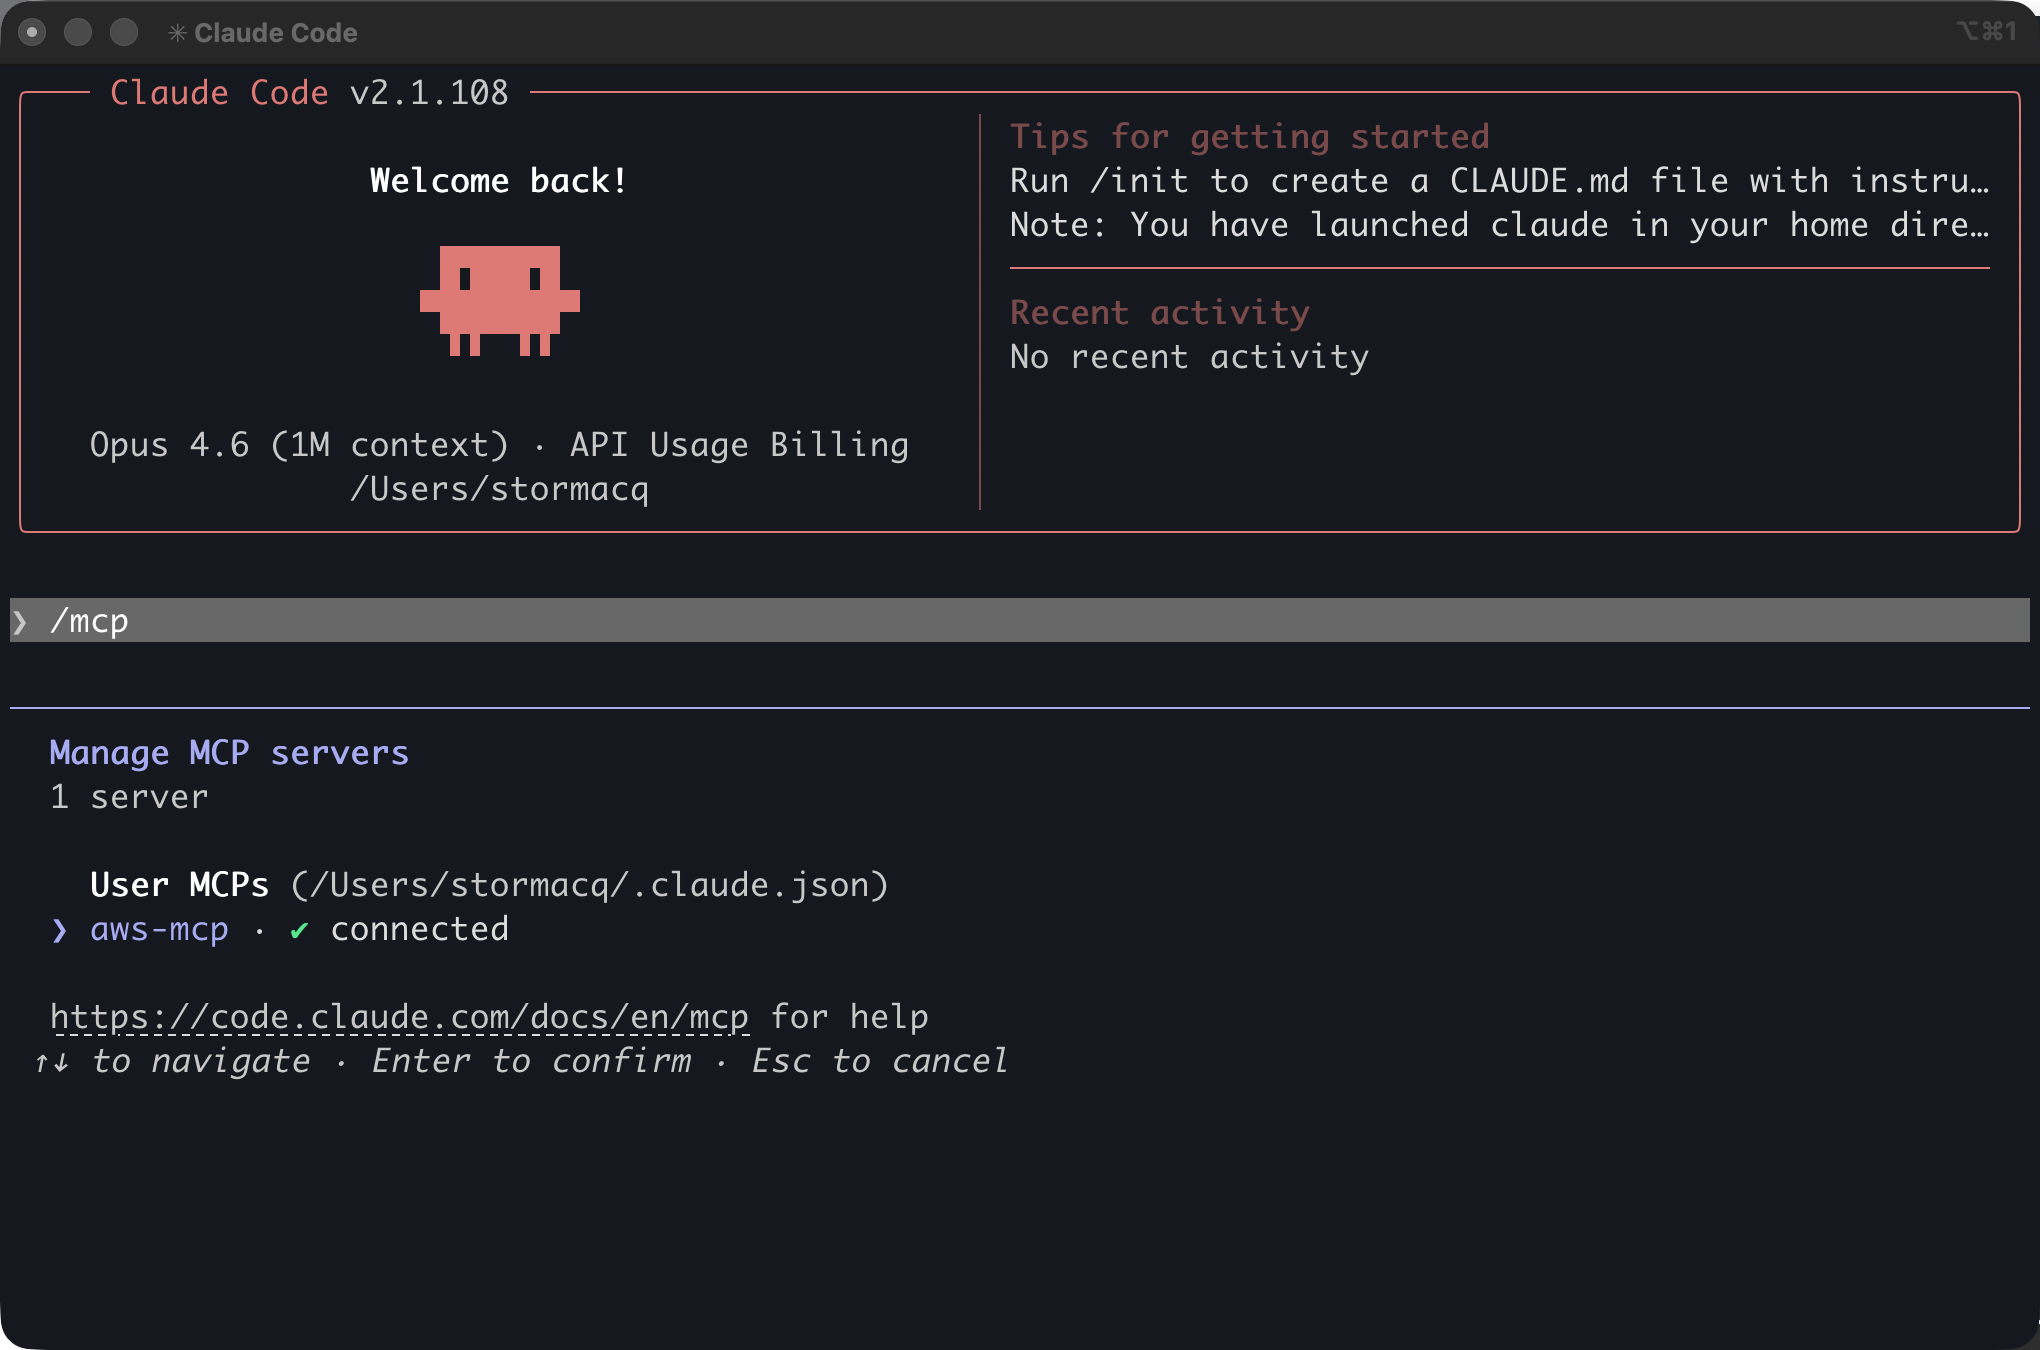
I start Claude Code and I type /mcp to verify the AWS MCP Server is correctly installed and can use my credentials.

Verify AWS MCP Server in Claude Code

I ask the same question: “how can I store embedding on S3”.

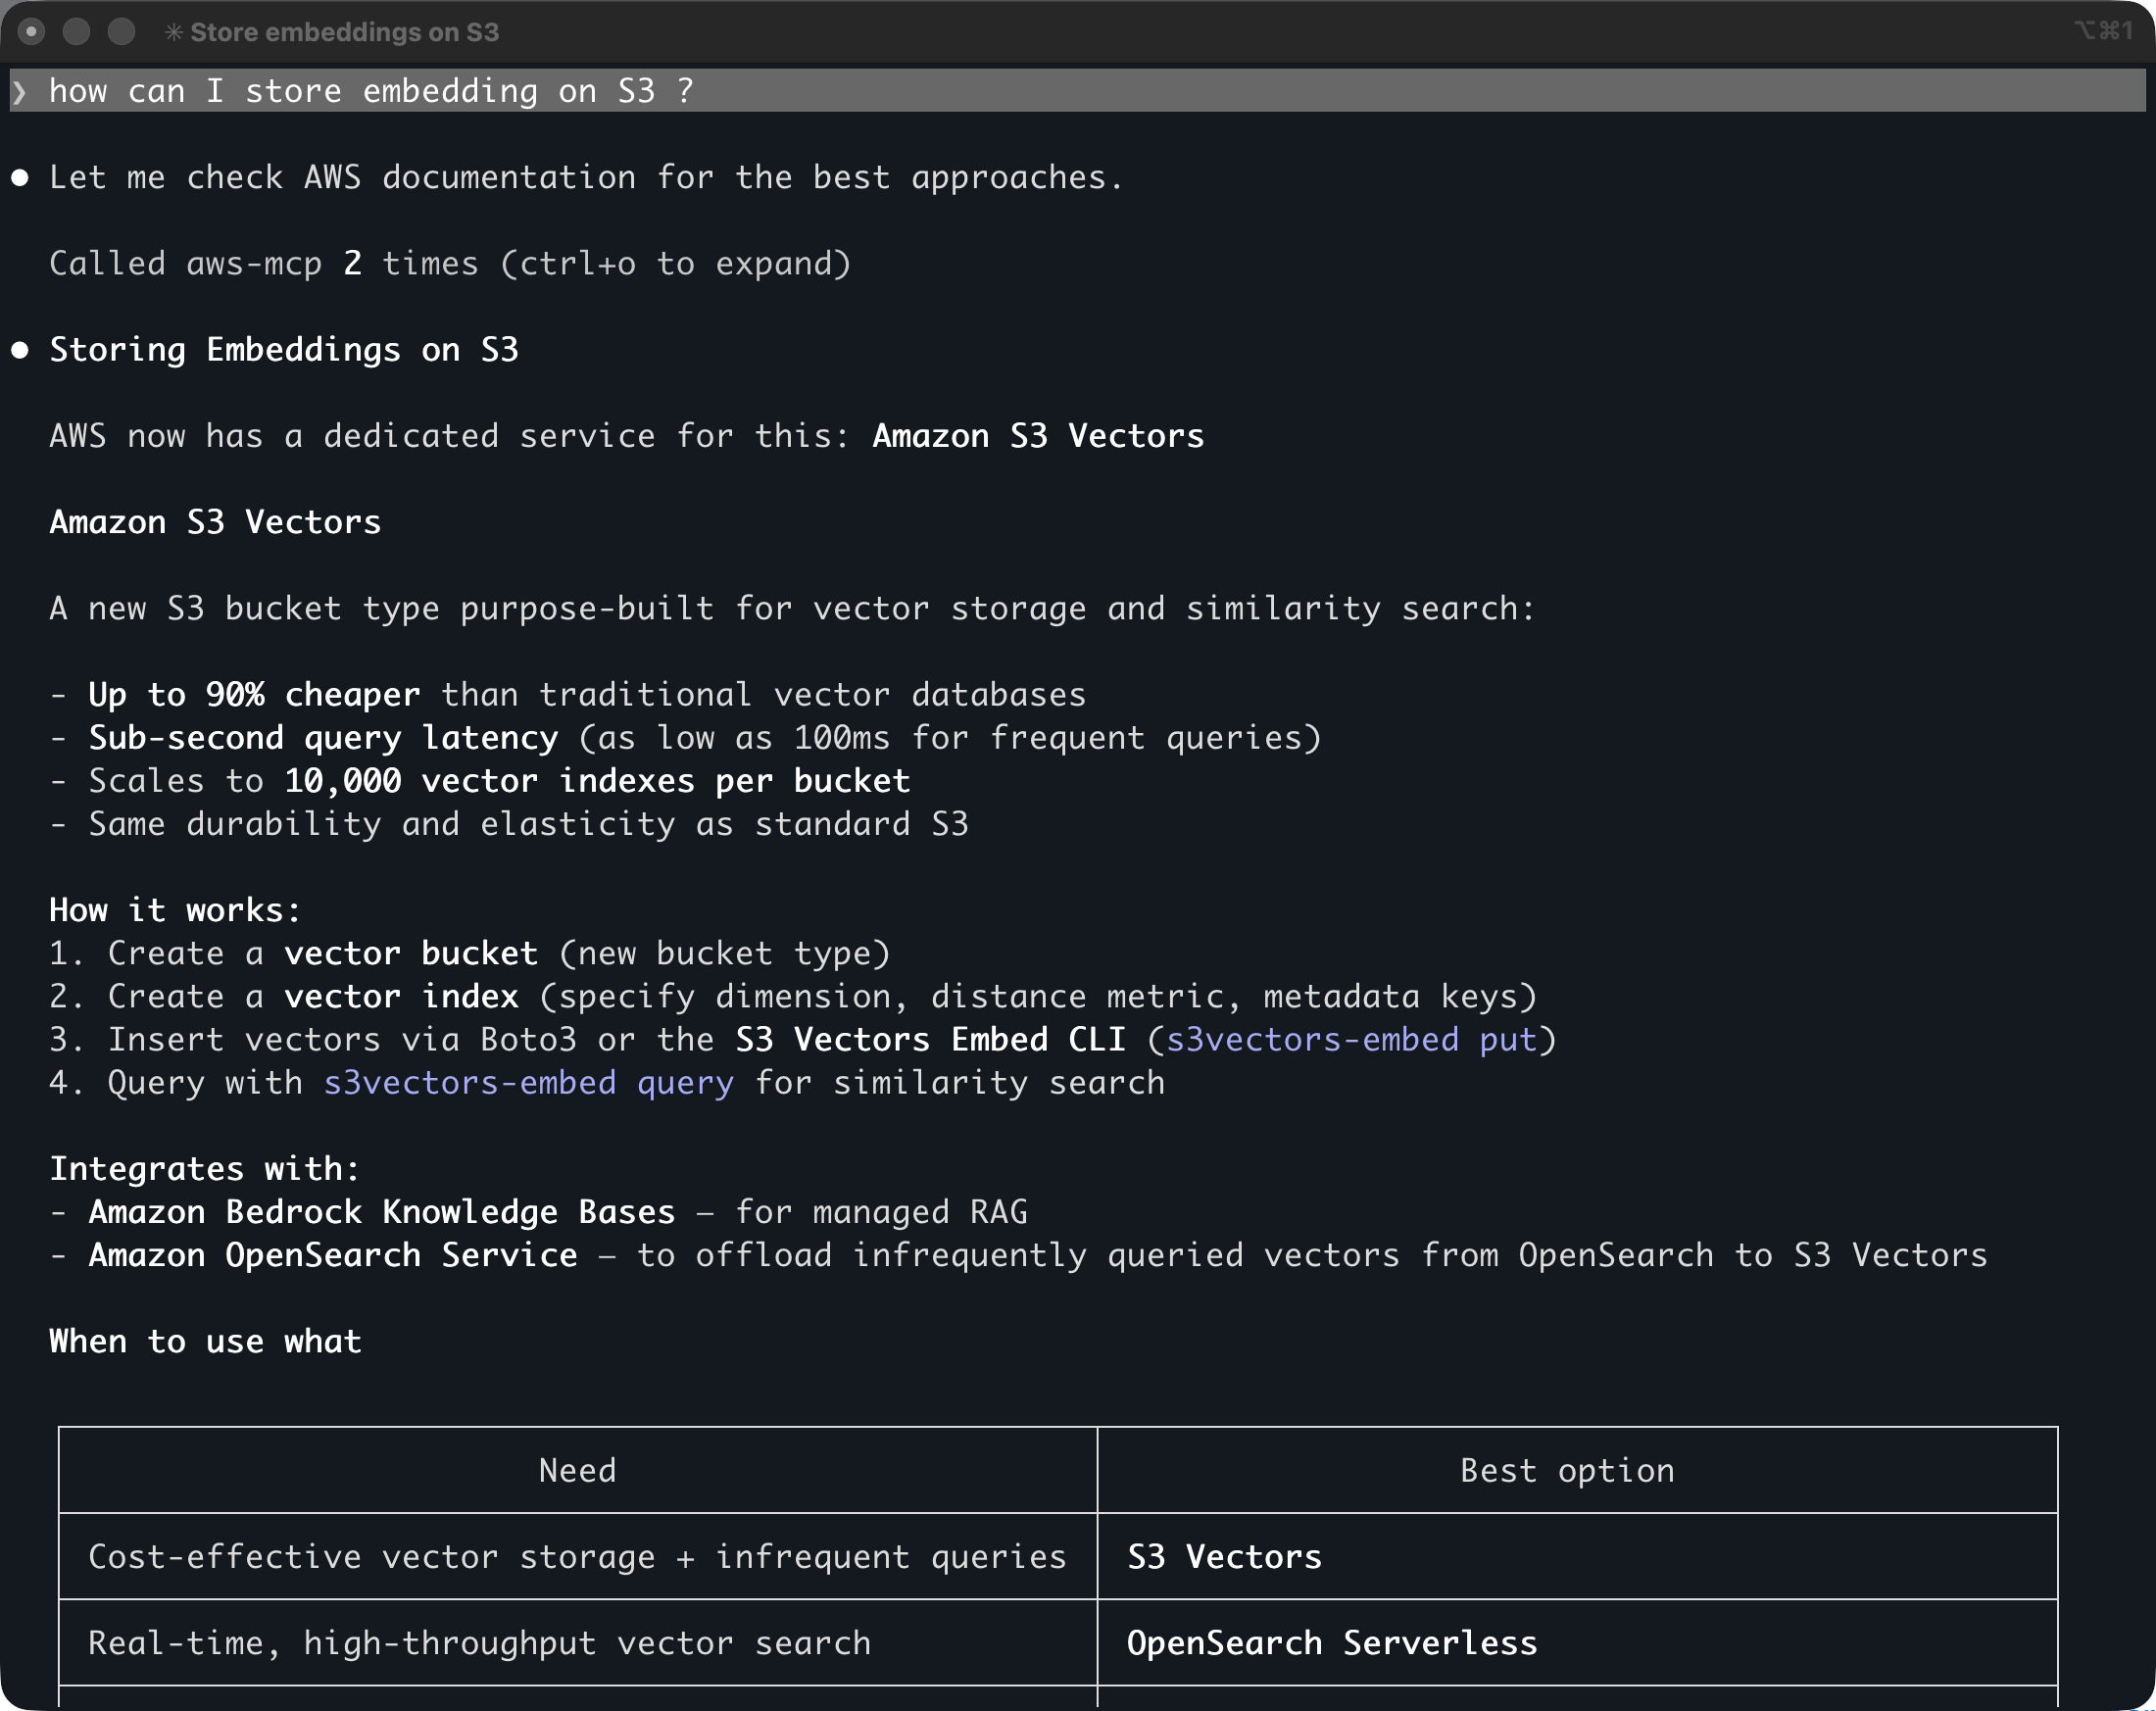
This time, Claude Code knows it has a tool it can use to answer the question. It asks me permission to invoke the aws___search_documentation tool. After a few seconds, I receive a correct answer: “AWS now has a dedicated service for this: Amazon S3 Vectors …”

Claude Code correct response about S3 Vectors

Pricing and availability
The AWS MCP Server is available today in the US East (N. Virginia) and Europe (Frankfurt) AWS Regions and can make API calls to any Region. There is no additional charge for the AWS MCP server itself. You pay only for the AWS resources you create and any applicable data transfer costs.

The AWS MCP Server works with Claude Code, Kiro, Cursor, and any MCP-compatible client. To get started, see the AWS MCP Server User Guide.

I have been waiting for something like this since I started using MCP tools in my AI agents early last year. The combination of current documentation, authenticated API access, and sandboxed script execution in a single server changes what an agent can actually do on AWS. I am curious what you build with it. Let me know in the comments.

— seb

Modernize your workflows: Amazon WorkSpaces now gives AI agents their own desktop (preview)

Post Syndicated from Micah Walter original https://aws.amazon.com/blogs/aws/modernize-your-workflows-amazon-workspaces-now-gives-ai-agents-their-own-desktop-preview/

Enterprises face a significant challenge when deploying AI agents: the desktop and legacy applications that power most business workflows are simply inaccessible to modern AI systems. According to a 2024 Gartner report, 75% of organizations run legacy applications that lack modern APIs, and 71% of Fortune 500 companies operate critical processes on mainframe systems without adequate programmatic access. For many organizations, this has meant choosing between delaying AI adoption or undertaking expensive and risky modernization projects.

Today, we are announcing that Amazon WorkSpaces now enables AI agents to securely operate desktop applications without requiring application modernization. The same managed virtual desktops that millions of employees use and trust can now also serve AI agents, turning WorkSpaces into infrastructure for scaling enterprise productivity, not just delivering it. Because agents operate within your existing WorkSpaces environment, there are no APIs to build, no application migrations to plan, and no new infrastructure to manage.

Some of our customers had an early opportunity to give their agents a WorkSpace. Chris Noon, Director, Nuvens Consulting shared with us, “WorkSpaces lets our clients give AI agents the same secure, governed desktop environment their employees already use — no custom API integrations, full audit trails, and enterprise-grade isolation out of the box. For regulated industries, that’s not a nice-to-have — it’s the baseline.”

Secure cloud desktop access for AI agents
With WorkSpaces, AI agents can securely access and operate desktop applications running inside managed WorkSpaces environments to complete complex business workflows. Agents authenticate through AWS Identity and Access Management (IAM) and connect via Workspaces with complete audit trails available through AWS CloudTrail and Amazon CloudWatch. Because agents operate within secure WorkSpaces environments rather than on local machines, your existing security controls and compliance policies remain fully intact.

Amazon Workspaces supports the industry-standard Model Context Protocol (MCP), which means WorkSpaces works with any agent framework, such as LangChain, CrewAI and Strands Agents.

Let’s try it out
To set up a WorkSpaces environment for AI agents, I started in the AWS Management Console by creating a new WorkSpaces Applications stack—the environment definition that controls how agents connect and what they’re allowed to do.

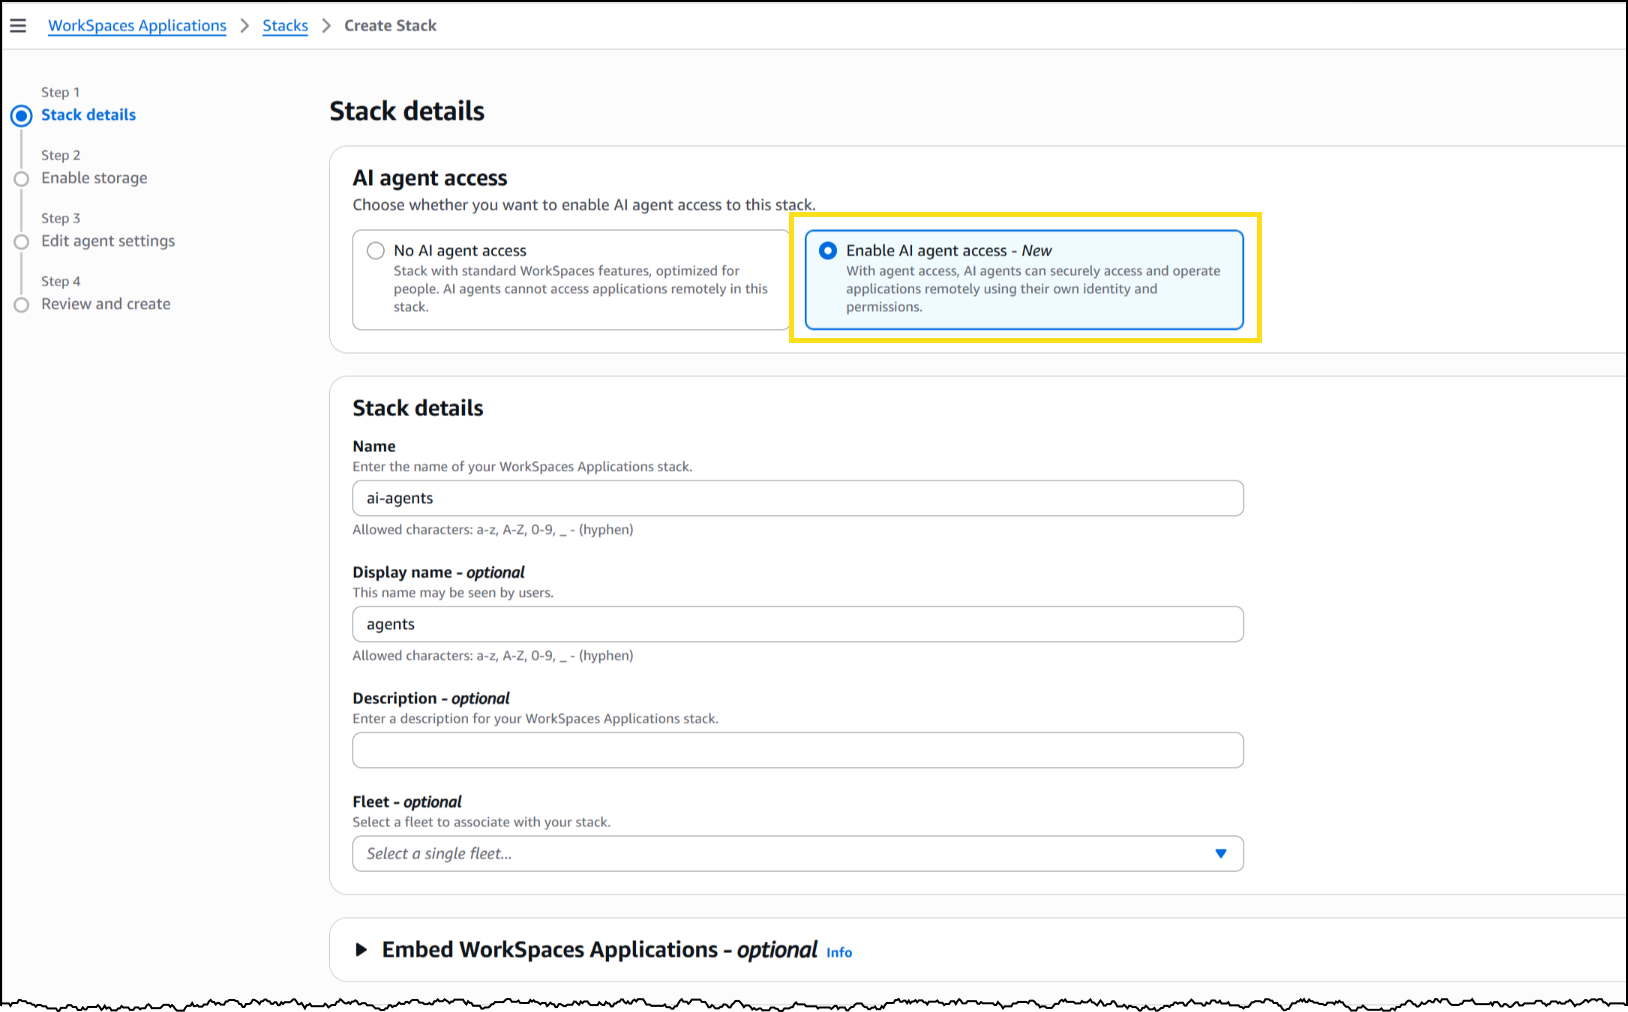
From the Amazon WorkSpaces console, I chose Create stack and configured the basics: name, fleet association, and VPC endpoints. In Step 3 of the stack creation workflow, I noticed the new AI agents section with two options. The first, No AI agent access, is the default configuration for standard WorkSpaces designed for people. The second, Add AI Agents, allows AI agents to securely access and operate applications using their own identity and permissions. I selected Add AI Agents to enable agent connections on this stack.

Workspaces Screenshot

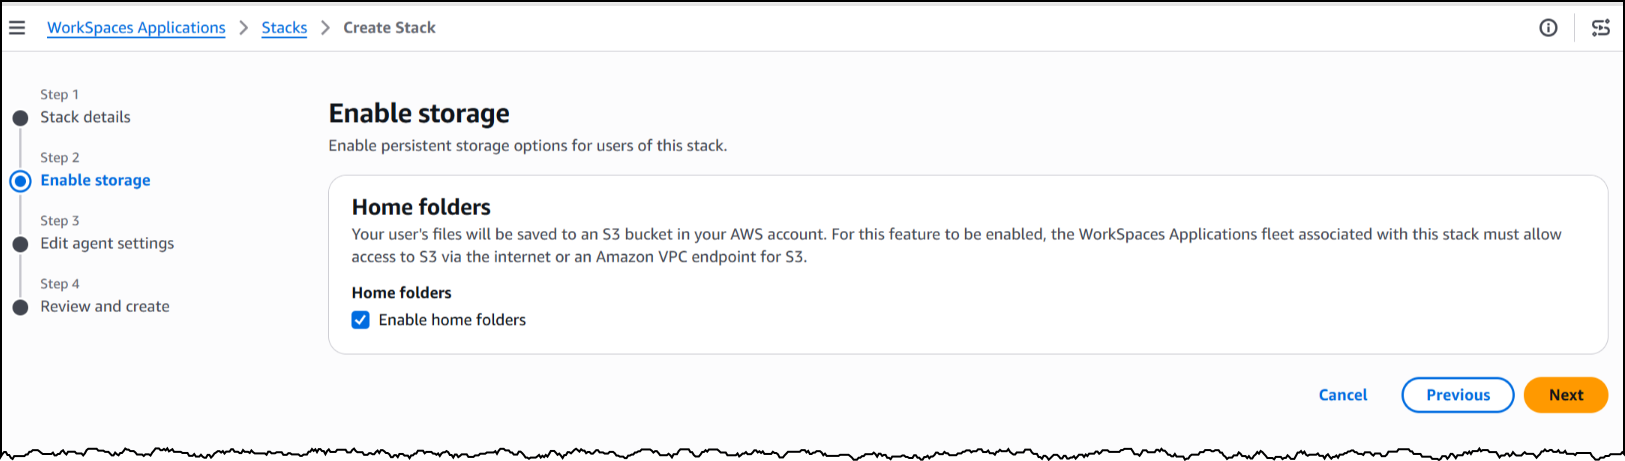
Next, I will enable storage before configuring the agent access settings to define how agents interact with the desktop.

Workspaces screenshot

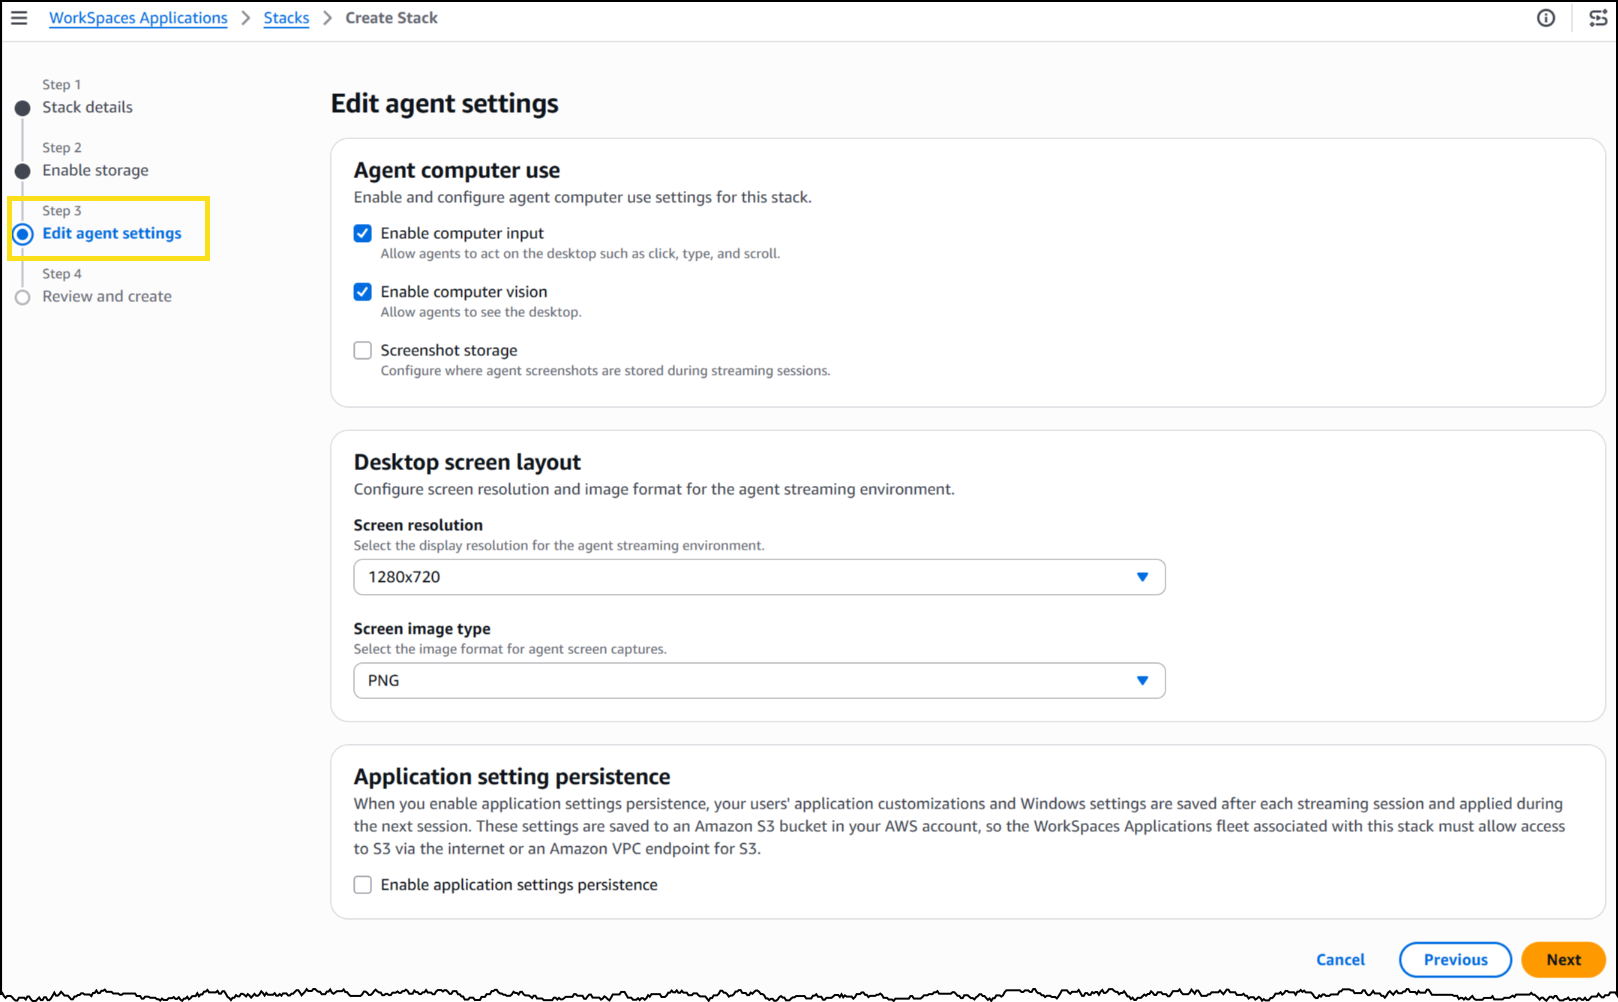
Under Agent features, I enabled three capabilities. Computer input allows the agent to click, type, and scroll within the desktop. Computer vision allows the agent to capture screenshots of the desktop, which is how it “sees” the application. Finally, screenshot storage configures where session screenshots are stored for audit and debugging.

Workspaces Screenshot

Under Desktop screen layout, I set the screen resolution to 1280×720 and image format to PNG. The resolution determines the fidelity of what the agent sees during a session—a complex application with dense UI elements might benefit from higher resolution, while a terminal-style interface works well at 720p.

Workspaces Screenshot

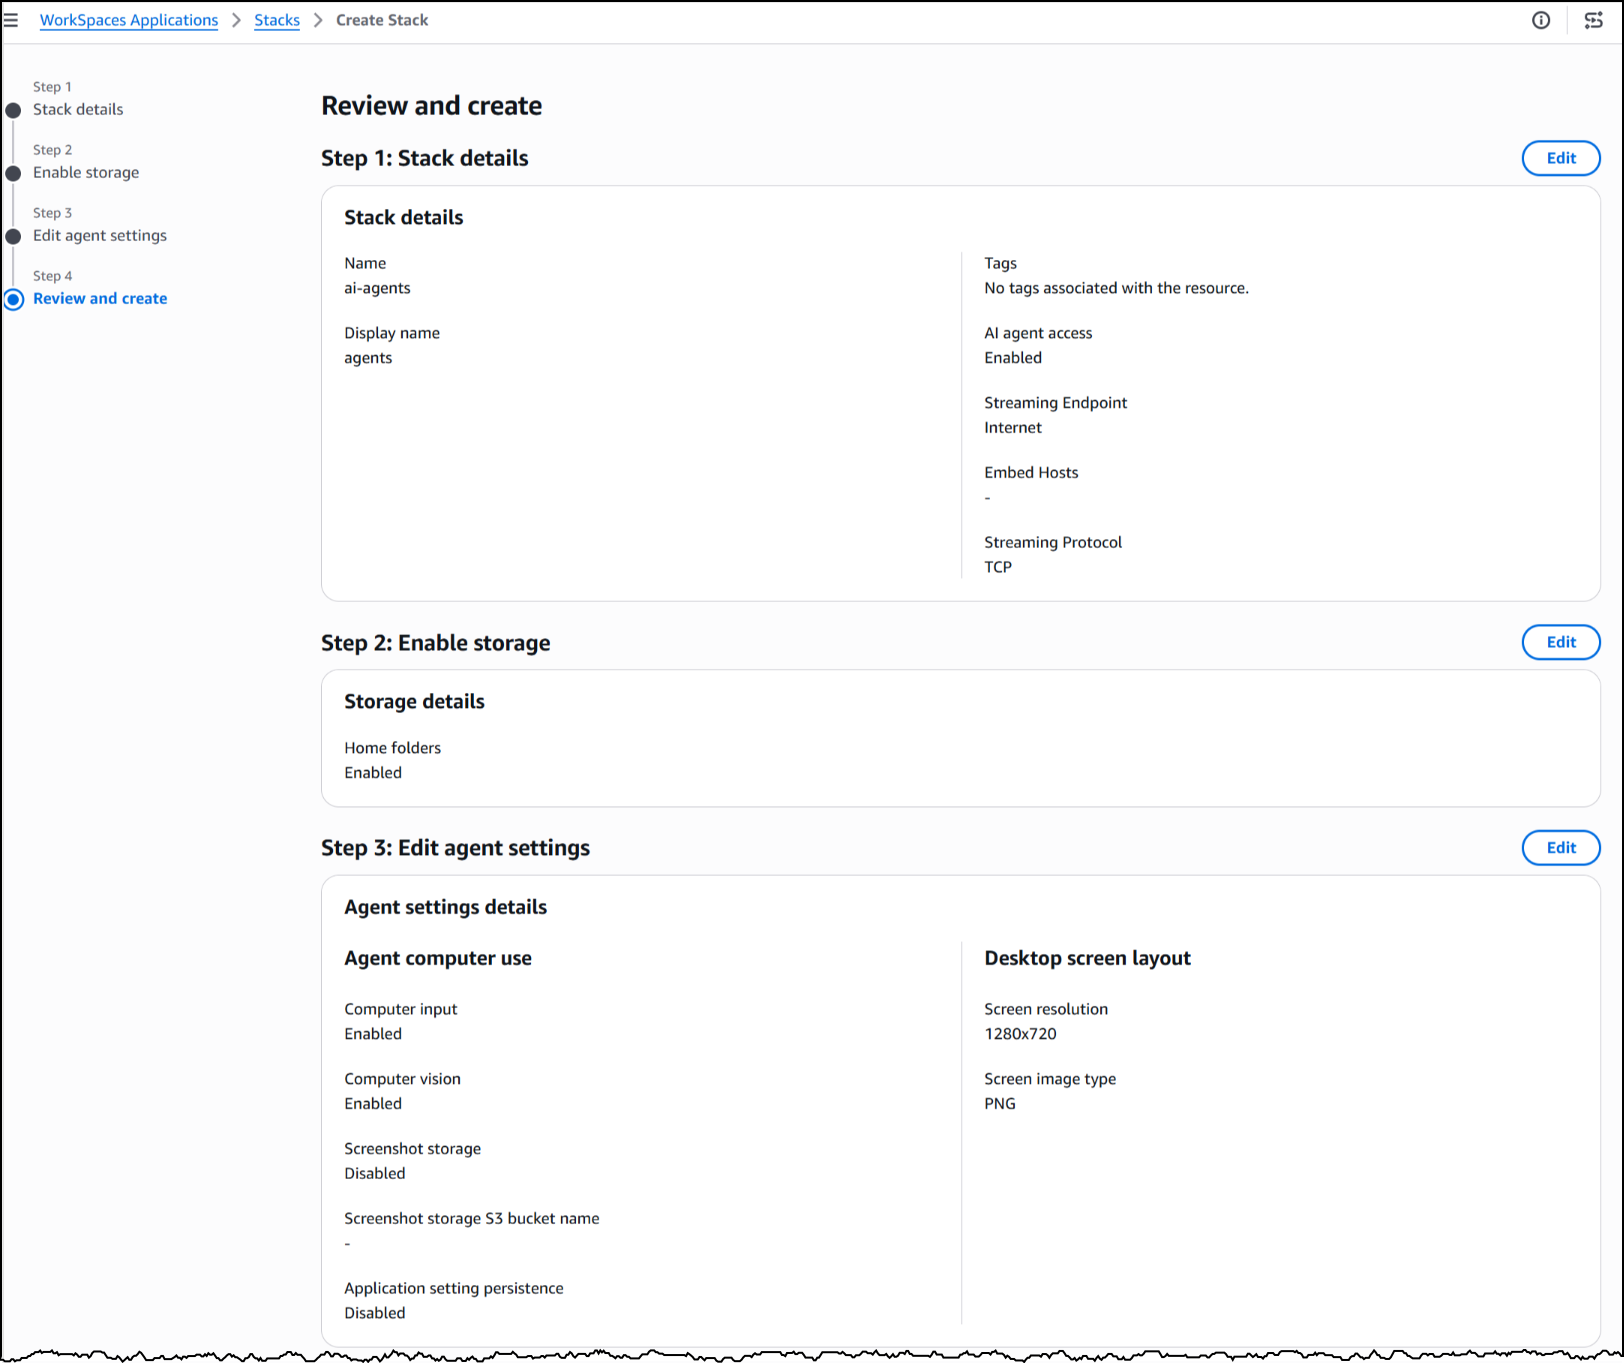
With my stack configured, WorkSpaces exposes a managed MCP endpoint. I pointed my agent framework to this endpoint, provided IAM credentials for authentication, and my agent began interacting with the desktop applications installed on the fleet’s image.

To see this in action, here’s an agent built with the Strands Agent SDK and Amazon Bedrock handling a prescription refill, looking up the patient record, searching for the medication, placing the order, and confirming a successful refill, all inside a sample pharmacy system with no API.

The application doesn’t know an agent is driving it. Nothing about the software was modified, rebuilt, or integrated. The agent worked with it exactly as it exists today.

Now available
This feature is available today in public preview at no additional cost in US East (N. Virginia, Ohio), US West (Oregon), Canada (Central), Europe (Frankfurt, Ireland, Paris), and Asia (Tokyo, Mumbai, Sydney, Seoul, Singapore) Regions.

Get started building today using our GitHub repo, or visit the WorkSpaces page for more details.

Five ways to use Kiro and Amazon Q to strengthen your security posture

Post Syndicated from Roger Nem original https://aws.amazon.com/blogs/security/five-ways-to-use-kiro-and-amazon-q-to-strengthen-your-security-posture/

A Monday morning security alert flags unauthorized access attempts, security group misconfigurations, and AWS Identity and Access Management (IAM) policy violations. Your team needs answers fast.

Security teams are using Kiro and Amazon Q Developer to handle repetitive tasks—scanning resources, drafting policies, and researching Common Vulnerabilities and Exposures (CVEs)—so engineers can focus on risk decisions and complex scenarios that require human judgment, resulting in faster threat response and more consistent security coverage.

This post shows you five ways to use Kiro and Amazon Q Developer to strengthen your AWS security posture based on the AWS Well-Architected Framework Security Pillar. Each technique builds on a common foundation described after the tool overview below.

About these tools

Amazon Web Services (AWS) gives customers choices when it comes to AI-assisted development and security automation. Whether you prefer Kiro’s agentic integrated development environment (IDE) experience or the deep integration of Amazon Q Developer into your existing AWS environment, both tools can help you implement the security practices described in this post. The right choice depends on your team’s workflow, and in many cases both tools are complementary and can be used together.

Kiro is an AI-powered, agentic, IDE designed by AWS for specification-driven development, combining natural language prompting with structured, intentional coding to generate, test, and deploy applications.

Amazon Q Developer is the generative AI assistant integrated into AWS development and cloud environments, designed to answer questions, generate code, troubleshoot issues, and automate operational tasks across AWS services.

For setup instructions and to learn more, see the Kiro documentation and Amazon Q Developer documentation.

1. Embed security best practices with persistent context

Providing AI assistants with the right context helps them produce more consistent and relevant results. Each of the five techniques in this post becomes significantly more powerful when your AI assistant already understands your organization’s security standards. Setting up persistent context first means every subsequent interaction builds on that foundation, and the results you get from triage, remediation, reviews, and policy development will better reflect your specific environment rather than generic best practices.

Without persistent context, you need to repeat the same security requirements in every prompt such as "enable encryption, use least privilege IAM settings, and enable logging," which leads to inconsistent results and missed controls. Amazon Q Developer IDE Plugin rules and Kiro steering files (CLI and IDE) solve exactly this problem: you can use them to codify your organization’s security standards so AI automatically builds secure infrastructure consistently, without requiring you to repeat requirements in every prompt. Both tools support this capability independently, so you can configure whichever fits your workflow, or use both together for coverage across your full development environment. The following steps show you how to get started with each.

For Amazon Q Developer:

  1. Create directory: .amazonq/rules/ in your project root.
  2. Create file: .amazonq/rules/security-standards.md.
  3. Paste your organization’s security standards in natural language (see “Example security standards context file” below).

For Kiro (steering files):

In Kiro, persistent context documents are called steering files. They give the agent ongoing awareness of your architecture decisions, coding standards, and security requirements across every interaction and every session.

  1. Create file: security-standards.md in your project root.
  2. Reference it in prompts: Using security-standards.md as context, create....

Pro tip: You can use Kiro itself to help you create steering files. Describe your security requirements in natural language and ask Kiro to generate a structured steering file for your review before saving and activating it. This means your AI assistant can help you build the very context it will later use, making the setup process faster and more thorough.

Example security standards context file:

# AWS Security Standards

## Identity and Access Management
- All IAM roles must use least privilege principles
- Require MFA for console access
- Enable IAM Access Analyzer for all accounts
- Rotate access keys every 90 days
- Use IAM roles for EC2 instances, never embed access keys

## Data Protection
- Enable encryption at rest for all storage services (S3, EBS, RDS)
- Use AWS KMS customer-managed keys for sensitive data
- Enable encryption in transit with TLS 1.2 minimum
- Implement S3 bucket policies denying unencrypted uploads
- Enable versioning and MFA delete for critical S3 buckets

## Infrastructure Protection
- Security groups must follow least privilege (no 0.0.0.0/0 on sensitive ports)
- Deploy resources in private subnets when possible
- Enable VPC Flow Logs for network monitoring
- Use AWS WAF for public-facing applications
- Implement Network ACLs as additional defense layer

## Detective Controls
- Enable CloudTrail in all regions with log file validation
- Configure CloudWatch alarms for security events
- Enable GuardDuty for threat detection
- Set up AWS Config rules for compliance monitoring
- Implement centralized logging with retention policies

## Incident Response
- Create SNS topics for security alerts
- Configure automated responses with AWS Lambda
- Maintain runbooks for common security incidents
- Enable AWS Systems Manager for secure instance access
- Implement automated backup and recovery procedure

What this unlocks:

Without persistent context, a prompt like Create a Lambda function to process customer data could produce a basic function with no encryption, logging, or IAM configuration. AI output is non-deterministic, meaning that without guidance it might or might not include those controls. Steering files and rules documents minimize those variables by providing stronger guidance as part of every prompt and inference input.

With your security standards embedded as in the example above, however, the same prompt generates a function with KMS-encrypted environment variables, a CloudWatch log group with 90-day retention, least-privilege IAM, VPC placement in private subnets, a dead-letter queue, and AWS X-Ray tracing—all automatically.

Where it works:

This persistent context approach applies across both tools and all infrastructure generation workflows:

  • Amazon Q Developer IDE Plugin: Rules in .amazonq/rules/ apply automatically to every code generation and review interaction.
  • Kiro: Steering files provide the agent with continuous architectural and security awareness across sessions and projects.

The shift-left impact:

This approach isn’t a replacement for your existing continuous integration and delivery (CI/CD) security automation. It’s a powerful complement to it, and that distinction matters. By embedding security standards directly into the development workflow, you shift security validation further left than pipeline checks can reach. Developers across your organization, not just security specialists, can generate infrastructure that meets your security standards from the first line of code. This scales security expertise into non-security roles, empowers development teams to self-serve on compliance requirements, and reduces the volume of findings that ever reach your automated pipeline checks.

The result is security functioning as an enabler of faster development rather than a gate that slows it down, and security engineers spending their time on policy design and complex risk decisions rather than remediating avoidable misconfigurations.

Measurable impact:

Track these metrics to quantify the value of persistent context:

  • Security findings during code review: Establish a 30–60 day baseline before enabling context files, then compare
  • Time from development to deployment: Track average cycle time before and after
  • Remediation cost: Research consistently shows defects fixed in development cost significantly less than those fixed in production. Track your own ratio for 60 days
  • Standards consistency: Audit a random sample of infrastructure pull requests for compliance with your top 10 policies

Implementation recommendation: Start by codifying your top 10 most frequently violated security policies as context. Measure the reduction in these specific findings over 30–60 days to quantify the impact on your team.

2. Accelerate security finding triage and investigation

AWS Security Hub consolidates findings from services such as Amazon GuardDuty, AWS Config, Amazon Inspector, and third-party security tools into a single dashboard, providing centralized security finding visibility and built-in triage capabilities across your AWS environment. AWS Security Hub Extended will bring even more capabilities into this mix, giving customers expanded control and additional opportunities to leverage the AI-assisted workflows described in this post at greater scale and with deeper integration across your security toolchain.

Kiro can complement Security Hub by helping you correlate findings across accounts, understand CVE context, and develop remediation approaches, including:

  • Query findings using natural language across multiple AWS accounts and AWS Regions
  • Understand specific CVEs and their potential impact on your infrastructure
  • Generate investigation queries for AWS CloudTrail and Amazon Virtual Private Cloud (Amazon VPC) Flow Logs
  • Correlate security events across different time periods and services
  • Access the latest AWS security documentation and best practices

How it works – Model Context Protocols:

To enable these capabilities, Kiro uses Model Context Protocols (MCPs)—a standardized way for AI assistants to securely connect with external tools, services, and data sources, enabling them to take actions, retrieve real-time information, and interact with APIs beyond their built-in capabilities.

Open source MCP servers for AWS are a suite of specialized MCP servers that enable Kiro to interact with AWS security services, providing real-time visibility into your security posture. To get started, configure security-focused MCP servers in your Kiro settings file (as shown in the following example). For full instructions on configuring MCP servers in Kiro, see the Kiro MCP documentation.

Note on authentication: Before querying Security Hub, verify you have configured valid AWS credentials for the target account. Set the AWS_PROFILE value to a named profile in your ~/.aws/credentials file that has the appropriate permissions, or configure credentials using the AWS Command Line Interface (AWS CLI) (aws configure). Without valid credentials for the target account, Kiro will not be able to retrieve findings.

{
    "mcpServers": {
        "awslabs.aws-api-mcp-server": {
            "command": "uvx",
            "args": ["awslabs.aws-api-mcp-server@latest"],
            "env": {
                "FASTMCP_LOG_LEVEL": "ERROR",
                "AWS_PROFILE": "<PROFILE>",
                "AWS_REGION": "us-east-1"
            },
            "timeout": 120000,
            "disabled": false
        },
        "awslabs.cloudtrail-mcp-server": {
            "command": "uvx",
            "args": ["awslabs.cloudtrail-mcp-server@latest"],
            "env": {
                "FASTMCP_LOG_LEVEL": "ERROR",
                "AWS_PROFILE": "<PROFILE>"
            },
            "disabled": false
        },
        "awslabs.iam-mcp-server": {
            "command": "uvx",
            "args": ["awslabs.iam-mcp-server@latest"],
            "env": {
                "FASTMCP_LOG_LEVEL": "ERROR",
                "AWS_PROFILE": "<PROFILE>"
            },
            "disabled": false
        }
    }
}

Configure the following security-focused MCP servers to get started:

  • AWS API MCP Server: Interact with Security Hub, GuardDuty, IAM Access Analyzer, and AWS Config through AWS CLI commands
  • CloudTrail MCP Server: Audit trail analysis and compliance monitoring
  • AWS IAM MCP Server: Manage IAM users, roles, policies, and permissions
  • AWS Knowledge MCP Server: Access up-to-date AWS security documentation and best practices

For a full list of available MCP servers, see the awslabs/mcp GitHub repository.

Example: querying Security Hub with Kiro:

  1. Open your terminal or Kiro IDE.
  2. Enter the following command:
"Show me all critical security findings from Security Hub in my production account ID <ACCOUNT ID>"

Example output:

> Found 4 critical security findings in account 123456789012:

## Configuration Issues (2)

1. SSM.7 - SSM documents block public sharing disabled
- Status: FAILED (since July 17, 2025)
- Impact: Systems Manager documents can be publicly shared
- Remediation: Enable block public sharing setting for SSM documents
- [Documentation](https://docs.aws.amazon.com/console/securityhub/SSM.7/remediation)

2. Config.1 - AWS Config not properly configured
- Status: FAILED (since March 4, 2025)
- Issue: Config isn't recording required IAM resource types (User, Role, Group, Policy)
- Standards affected: CIS, NIST 800-53, PCI DSS, AWS Foundational Security
- Remediation: Enable recording for IAM resources in AWS Config
- [Documentation](https://docs.aws.amazon.com/console/securityhub/Config.1/remediation)

## Vulnerabilities (2)

3. CVE-2020-36242 in Lambda function: MyLambdaOne
- Package: cryptography version 3.2.1
- CVSS Score: 9.1 (Critical)
- Issue: Integer/buffer overflow in Fernet encryption class
- Fix: Upgrade to cryptography 3.3.2
- Function: SPC-1233HH5R-MyLambdaOne-lUh3ESH0MdXF

4. CVE-2020-36242 in Lambda function: AutoUpdateMyLambdaOne
- Package: cryptography version 3.2.1
- CVSS Score: 9.1 (Critical)
- Same vulnerability as above
- Function: SPC-1233HH5R-AutoUpdateMyLambdaOne-d9HIBfxThbFW

Real-world impact:
Security finding triage that previously required navigating multiple consoles, correlating logs manually, and researching CVE databases can be accelerated significantly. Teams that have integrated AI-assisted triage into their Security Hub workflows report reducing mean time to triage for critical findings from hours to minutes, enabling faster containment and more consistent coverage across accounts.

3. Accelerate remediation of security findings in your infrastructure as code

AI assistants can scan your infrastructure code and flag security issues with specific fix recommendations. However, implementing these changes requires careful review, testing, and validation before any changes reach production.

Important: AI-generated remediation suggestions must be reviewed by a qualified security engineer before implementation. Automated application of AI-generated changes without human validation can introduce unintended misconfigurations or service disruptions. Treat AI output as a starting point, not a finished product.

The workflow:
You can execute this workflow in either Kiro or Amazon Q Developer, depending on which tool fits your existing development environment:

  1. Ask Kiro or Amazon Q Developer to scan your infrastructure files and identify security gaps.
  2. Review AI-generated remediation suggestions with your security team.
  3. Test changes in non-production environments.
  4. Validate using AWS security services such as IAM Access Analyzer, AWS Config, and Security Hub.
  5. Deploy to production with monitoring and rollback procedures in place.

Example prompt:

"Scan my infrastructure at /path/to/templates, identify all S3 buckets without encryption, enable AES-256 encryption, add bucket policies to deny unencrypted uploads, and provide the deployment command"

What happens:

The AI assistant analyzes your infrastructure files, whether written in AWS CloudFormation, Terraform , or AWS Cloud Development Kit (AWS CDK), and identifies resources that violate security best practices. It then implements controls such as encryption at rest using AWS Key Management Service (AWS KMS) or Amazon Simple Storage Service (Amazon S3)-managed keys, adds bucket policies enforcing encryption in transit, configures public access blocks, and generates the exact deployment command with a change preview so you can review what will be modified before anything is applied.

Based on the example security standards context file above, the following controls would be applied across all generated infrastructure: encryption at rest and in transit, least-privilege IAM policies, security group optimizations, VPC configurations, logging enablement, and backup and recovery settings.

Validation required:
AI-generated configurations deserve the same thoughtful review as other infrastructure code. Even a policy that looks correct on the surface might need tuning to match your organization’s least-privilege standards, or encryption settings might need adjusting to satisfy specific compliance requirements. Running those changes through a non-production environment and having a human confirm the results before anything reaches production are part of good infrastructure practices, whether the code was written by a person or generated by AI.

Real-world impact:

Identifying non-compliant resources across multiple accounts manually can take many hours and generating remediation templates for each resource can add significant time. Security teams that have adopted AI-assisted infrastructure scanning report spending less time on manual identification and template generation, and with AI assistance the same identification and drafting work can be completed in much less time. Customers report that a full remediation cycle that previously occupied their team for the better part of a day can be completed in under an hour when AI handles the scanning and template generation. It is worth noting that manual remediation time grows considerably at scale, as remediating dozens of non-compliant resources is not a linear exercise. Validation time in non-production environments remains essential regardless of how the remediation was generated, and should always be factored into your planning.

4. Perform in-depth security reviews

Amazon Q Developer and Kiro can analyze your infrastructure code and identify potential security issues across multiple categories aligned with the AWS Well-Architected Framework Security Pillar.

Using Amazon Q Developer:

  1. Open your infrastructure file in your IDE.
  2. Select the code you want to review.
  3. Open the context menu and choose Send to Amazon Q, then choose Optimize.
  4. Select Focus on security best practices.

Using Kiro:

  1. Open your infrastructure file in Kiro.
  2. Enter a natural language prompt such as: Perform a comprehensive security review of this CloudFormation template and identify all deviations from our standards.
  3. Kiro will automatically apply your steering files as additional context when generating its response.
  4. Review the findings and iterate with follow-up prompts.

Security categories evaluated: For the complete, up-to-date list of security categories and controls, see the AWS Well-Architected Framework Security Pillar documentation. Current categories include but are not limited to:

  • Identity and access management: Overly permissive IAM policies, missing multi-factor authentication (MFA) requirements, unused credentials and access keys, cross-account access risks
  • Detective controls: CloudTrail logging configuration, Amazon CloudWatch alarm coverage, GuardDuty enablement status, and AWS Config rule implementation
  • Infrastructure protection: Security group misconfigurations, public subnet exposure, missing AWS WAF rules, unencrypted network traffic
  • Data protection: Storage encryption status, KMS key rotation policies, backup configurations, S3 bucket access controls
  • Incident response: Amazon Simple Notification Service (Amazon SNS) alerting setup, log retention policies, automated response mechanisms

Example output:

Security Recommendations:
- Enable S3 bucket encryption with KMS: Critical
- Implement least privilege IAM policies: High
- Enable GuardDuty threat detection: High
- Configure VPC Flow Logs: Medium
- Add WAF rules for API Gateway: Medium
- Enable CloudTrail in all regions: Critical
- Implement automated backup policies: High

Total security improvements: 23 findings across 5 Well-Architected pillars

Keeping your configuration files current:

A security architect review remains valuable for keeping your steering files and rules documents complete and current. The goal is an AI assistant that already understands your environment, not one that needs correcting after every interaction. Treat your configuration files as living documents and update them when your security standards evolve, when new services are adopted, or when post-incident reviews reveal gaps. As this post notes, project rules reduce architectural drift and help maintain consistency as AI agents operate more autonomously.

Real-world impact:

Security reviews that previously required a security engineer to manually inspect infrastructure templates line by line can be completed in significantly less time with AI assistance. Teams using AI-assisted security reviews as a pre-commit gate—before code reaches CI/CD pipeline checks—report catching a meaningful portion of security findings earlier in the development cycle where they are faster and less costly to address. Integrating this review step into pull request workflows means security validation happens continuously rather than only at deployment gates.

5. Assist with service control policy development

You can use AWS Organizations Service Control Policies (SCPs) to apply preventive controls consistently across every account in your organization, enforcing security baselines without relying on individual account administrators. Kiro can generate initial SCP drafts from natural language security requirements, speeding up the drafting and iteration process considerably. Because SCPs are preventive controls that can’t be bypassed by administrators, misconfigurations can cause organization-wide service disruptions, making expert validation and staged testing essential before any SCP reaches production.

Step 1: Generate an SCP draft:

Describe your security requirements in natural language:

"Create an SCP with these security controls:
- Deny creation of S3 buckets without encryption
- Require MFA for IAM user console access
- Prevent public RDS snapshots
- Deny security group rules allowing 0.0.0.0/0 on sensitive ports
- Enforce encryption for all EBS volumes
- Require VPC Flow Logs on all VPCs
- Deny IAM policy creation without approval tags
- Restrict resource creation to approved regions only"

Kiro generates a complete SCP policy JSON with proper deny statements, condition keys for MFA and encryption enforcement, resource-level restrictions, and regional compliance requirements.

Step 2: Validate and lint the SCP:

Use Kiro or Amazon Q Developer to assist with policy linting and initial testing as a first layer of validation. IAM Policy Autopilot, available as a Kiro Power with one-click installation directly from the Kiro IDE, can analyze your application’s usage and generate necessary permissions based on the SDK calls it discovers. IAM Policy Autopilot also integrates as an MCP server with Kiro, Amazon Q Developer, and other MCP-compatible coding assistants, making it a natural part of your existing workflow rather than a separate tool.

"Review this SCP JSON for syntax errors, overly broad deny statements, and missing condition keys. Flag any statements that could unintentionally block legitimate operations."

The IAM Policy Simulator then adds another layer of validation on top of the AI-assisted linting, so you can test policy behavior, verify condition keys are correctly applied, and confirm that no legitimate operations are unintentionally blocked. IAM Policy Autopilot complements existing IAM tools such as IAM Access Analyzer by providing functional policies as a starting point, which you can then validate using IAM Access Analyzer policy validation or refine over time with unused access analysis. Together, these tools form a layered validation approach where each one strengthens the output of the previous step.

Step 3: Test in a sandbox environment:

Create a test organizational unit (OU) with non-production accounts and apply the SCP to the test OU. Attempt operations that should be blocked and confirm that no legitimate operations are unintentionally blocked. Use Kiro to pre-validate your infrastructure code against the proposed SCP before sandbox testing:

"Analyze my current infrastructure against this proposed SCP and identify resources that would be non-compliant"

This scan covers your infrastructure code files. For live account scanning across your organization, use the following AWS services:

  • AWS Config with the Config Aggregator and Conformance Packs for continuous compliance monitoring across your organization.
  • IAM Access Analyzer for automated reasoning-based analysis of external access, internal access, and unused permissions.
  • Account Assessment for AWS Organizations for bulk scanning of identity-based, resource-based, and service control policies across all accounts.
  • Security Hub for centralized aggregation of compliance findings and security scores across your entire organization.

Step 4: Security architect review:

Engage your security architects to identify potential risks and verify the policy aligns with your security framework. Check for conflicts with existing SCPs by reviewing all SCPs attached to parent OUs and the root in the AWS Organizations console. Use the IAM Policy Simulator to test interactions between policies and verify that emergency access procedures ( SEC03-BP03 Establish emergency access process – Security Pillar and SEC10-BP05 Pre-provision access – Security Pillar) remain functional before any production rollout.

Step 5: Staged rollout:

Deploy to development accounts first and monitor for policy violations and operational issues. Gradually expand to additional environments and maintain documented rollback procedures throughout the process.

Important: It’s strongly recommended not to deploy AI-generated SCPs directly to production without thorough expert review and staged testing. A misconfigured SCP can cause organization-wide service disruptions affecting every account in your organization.

Real-world impact:

SCP drafting that previously required security architects to write and iterate on complex JSON policy documents manually, often spanning multiple review cycles over several days, can be condensed when AI handles the initial drafting and linting. Your architects can then focus their time on policy design, edge case analysis, and organizational impact assessment rather than JSON syntax and structure.

Responsible implementation framework

Adopting AI-assisted security workflows is most effective when introduced gradually, with clear validation gates at each stage. The following two-phase approach gives your team time to build confidence, measure results, and establish the internal practices needed before expanding to production environments.

  • Phase 1: Development and testing (weeks 1–4): Start by testing AI-generated security controls in isolated development accounts. Validate functionality, identify edge cases, and deploy to a dedicated testing environment with thorough security validation. Use IAM Access Analyzer, AWS Config, and Security Hub to verify that generated controls behave as expected. This phase is also the right time to build internal expertise across both your security team and your development teams, so that knowledge of what works and what requires human review is shared broadly from the start.
  • Phase 2: Staging and production (week 5 and later): Apply the validated controls to a staging environment that mirrors production. Conduct penetration testing where appropriate and validate that monitoring and alerting function correctly before expanding further. Gradually roll out to production accounts with continuous monitoring in place. Maintain rollback procedures throughout and establish feedback loops so that lessons learned in production flow back into your steering files, rules documents, and validation processes over time.

Key takeaways

What distinguishes the approach in this post from general guidance on AI coding assistants is the specificity of the security integration. There’s no shortage of content about how AI assistants accelerate development. What this post focuses on is how to configure both Kiro and Amazon Q Developer to perform security-specific tasks: triaging findings from Security Hub, remediating infrastructure code vulnerabilities against your organization’s defined standards, conducting Well-Architected security reviews, drafting and validating SCPs, and generating secure-by-default infrastructure through persistent context that reflects your environment rather than generic defaults.

Kiro is an agentic IDE that helps you go from prototype to production with spec-driven development, and its steering files give the agent persistent awareness of your security standards across every session. Amazon Q Developer complements this by providing deep integration into your existing AWS environment and IDE workflows. Together, these tools extend your security team’s reach into every stage of the development lifecycle, scale security expertise into development teams, and reduce the gap between when vulnerabilities are introduced and when they are caught. As the AWS Well-Architected Framework Security Pillar establishes, embedding security early and consistently across the development process is foundational to a strong security posture.

These five techniques aren’t about replacing your security controls. They’re about making security a natural part of how your teams build on AWS, regardless of whether they’re security specialists or application developers. In addition to the five techniques covered in this post, the following AWS capabilities complement this approach and are worth exploring for a more complete picture:

  • Amazon Inspector is a vulnerability management service that continually scans AWS workloads for software vulnerabilities, code vulnerabilities, and unintended network exposure. It automatically discovers and scans Amazon EC2 instances, container images in Amazon ECR, AWS Lambda functions, and first-party code repositories. Amazon Inspector integrates directly into CI/CD pipelines through plugins for Jenkins, TeamCity, GitHub Actions, and Amazon CodeCatalyst, which teams can use to catch vulnerabilities before deployment. Its code security capabilities include Static Application Security Testing (SAST), Software Composition Analysis (SCA), and infrastructure as code (IaC) scanning, with native integration to GitHub and GitLab. All findings are surfaced directly in Security Hub for centralized visibility and response across your organization.
  • Amazon Q Developer security scanning provides real-time security issue detection in the IDE, including SAST scanning for security vulnerabilities, secrets detection, IaC security evaluation, and software composition analysis for third-party dependencies. These capabilities are available across JetBrains, Visual Studio Code, and Visual Studio.
  • Kiro Powers are curated and pre-packaged MCP servers, steering files, and hooks validated by Kiro partners to accelerate specialized development and deployment use cases. Security-relevant Kiro Powers include the IAM Policy Autopilot Kiro Power for baseline IAM policy generation and the real-time coding security validation MCP server pattern for Kiro.
  • AWS Security Agent is a frontier AI agent that proactively secures your applications throughout the development lifecycle. Security teams define organizational security requirements once in the AWS Security Agent console, such as approved encryption libraries, authentication frameworks, and logging standards, and AWS Security Agent then automatically validates these requirements throughout development by evaluating architectural documents and code against your defined standards. It provides three core capabilities: design security review for architecture documents, code security review that automatically analyzes pull requests against your defined standards across connected repositories, and on-demand penetration testing that discovers, validates, and reports vulnerabilities through sophisticated multi-step attack scenarios customized for each application. When vulnerabilities are found, AWS Security Agent creates pull requests with ready-to-implement fixes directly in your code repository. Customers report that AWS Security Agent compresses penetration testing timelines from weeks to hours, transforming penetration testing from a periodic bottleneck into an on-demand capability that reduces risk exposure and scales security reviews to match development velocity.
  • AWS Security Hub automated response and remediation provides pre-built playbooks for common findings using AWS Systems Manager Automation, enabling your team to act on findings faster and more consistently.

Getting started

If you’re new to AI-assisted security workflows, the following week-by-week approach gives your team a practical path forward without overextending before the foundation is in place.

  • Weeks 1 and 2: Set up your persistent context files with your top 10 security policies as described in the foundational setup section above. Configure MCP servers in Kiro for Security Hub and CloudTrail access and verify that credentials are correctly configured for your target accounts.
  • Weeks 3 and 4: Run your first AI-assisted security review on a non-production infrastructure template. Compare the findings against your last manual review to establish a baseline for measuring impact over time.
  • Weeks 5 and 6: pilot AI-assisted SCP drafting for one new preventive control. Run the full validation workflow including AI-assisted linting, IAM Policy Autopilot, and the IAM Policy Simulator before any production application.
  • From that point forward: Measure the metrics outlined in the foundational setup section, update your steering files and rules documents as your standards evolve, and share findings across your security team, development teams, and platform engineering teams. The knowledge of what works and what requires human judgment is valuable to everyone who touches infrastructure in your organization.

Conclusion

Kiro and Amazon Q Developer give security teams practical tools to accelerate threat response and maintain consistent security coverage by handling the tasks that consume the most time with the least strategic value: scanning for known misconfigurations, drafting policy JSON, researching CVEs, and generating secure infrastructure. These AI assistants are most effective when paired with security engineers, as they accelerate assessments and code generation while human review, policy design, and risk judgment remain essential throughout.

By implementing the five techniques outlined in this post, starting with embedding security best practices through persistent context and then applying that foundation to Security Hub finding triage, infrastructure code remediation, in-depth Well-Architected security reviews, and SCP development, your team can strengthen your AWS security posture while maintaining the standards your organization requires.

AWS services such as Security Hub, IAM Access Analyzer, AWS Config, and CloudTrail provide the foundation for these AI-assisted workflows, enabling centralized visibility and automated validation of security controls across your environment. Emergency access procedures should be established and validated before deploying any preventive controls such as SCPs, following the break-glass guidance in the AWS Well-Architected Security Pillar and the AWS Prescriptive Guidance for break-glass access.

Start small with non-production environments, establish clear validation processes, measure results, and gradually expand your use of AI assistants as your team builds expertise and confidence. The result is faster threat response, more consistent security coverage, and security engineers focused on complex decisions rather than repetitive tasks.

Additional resources

If you have feedback about this post, submit comments in the Comments section below
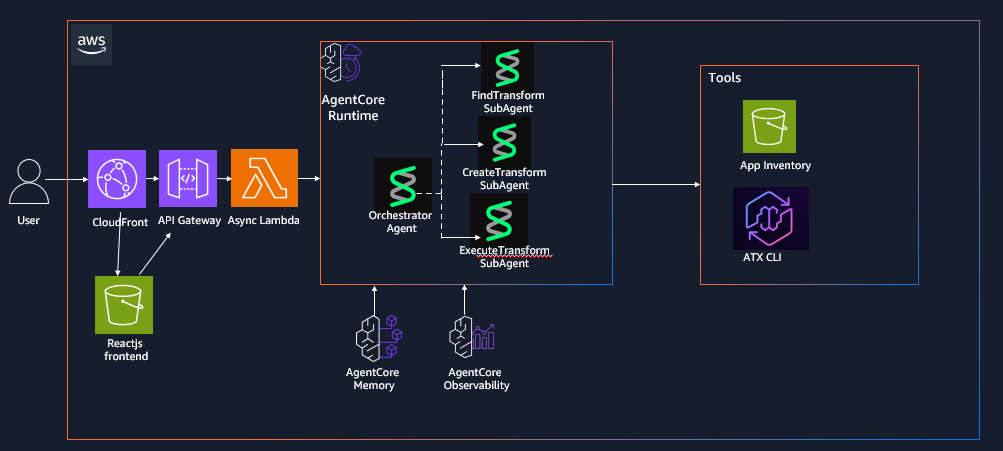

Roger Nem

Roger Nem

Roger is an Enterprise Technical Account Manager (TAM) supporting Healthcare & Life Science customers at Amazon Web Services (AWS). As a Security Technical Field community specialist, he helps enterprise customers design secure cloud architectures aligned with industry best practices. Beyond his professional pursuits, Roger finds joy in quality time with family and friends, nurturing his passion for music, and exploring new destinations through travel.

Security posture improvement in the AI era

Post Syndicated from Celeste Bishop original https://aws.amazon.com/blogs/security/security-posture-improvement-in-the-ai-era/

It’s only been a few weeks since Anthropic announced the Claude Mythos Preview model and launched Project Glasswing with AWS and other leading organizations. This has generated a lot of discussion about the future of cybersecurity and what the ever-increasing capabilities of foundation models mean to organizations.

As AWS CISO Amy Herzog pointed out in the Project Glasswing announcement, “At AWS, we build defenses before threats emerge, from our custom silicon up through the technology stack. Security isn’t a phase for us; it’s continuous and embedded in everything we do.”

Read more from Amy about this in Building AI defenses at scale: Before the threats emerge.

While the discussion around the future of cybersecurity is important, the only thing we know for certain is that organizations need to be able to react quickly to the rapid changes AI is bringing to technology and business in general. And you can’t react quickly if your security fundamentals aren’t dialed in.

The security hygiene gap

It’s easy to assume you have the foundational security elements covered, or to overlook some completely. Basic security use cases like identity management, threat detection, vulnerability management, data protection, and network security can be inconsistently implemented across cloud environments. While AI is reshaping the security landscape, strong security fundamentals continue to be essential for every organization, regardless of size or industry.

These are the security basics that matter whether or not you’re adopting AI: patching consistently, enforcing least-privilege access, enabling logging and monitoring, encrypting data at rest and in transit, and reviewing security configurations regularly. When these fundamentals are in place, you’re better positioned to take advantage of AI-driven tools and respond to newly discovered vulnerabilities, wherever they come from.

While the concepts that drive security fundamentals are universal, implementing them in your environment is best done with an understanding of the context unique to your organization. That’s why we have a multitude of freely available materials—like the AWS Well-Architected Framework—that you can use to help ask the right questions and implement changes in your environment. We also offer programs like the Security Health Improvement Program (SHIP) to help you improve your security posture through prescriptive guidance and continuous improvement.

What is the Security Health Improvement Program (SHIP)?

SHIP is a no-cost program available to every AWS customer, regardless of support tier. SHIP provides a proven, data-driven methodology to:

  • Assess your current security posture using data from your AWS environment
  • Identify specific opportunities to improve across 10 core security use cases
  • Build a prioritized action plan tailored to your environment
  • Establish a mechanism for continuous security improvement

The program is led by AWS Solutions Architects and Technical Account Managers who take you through a personalized report, contextualize findings for your environment, and help you build a prioritized action plan.

Why SHIP matters in the AI era

Project Glasswing highlights an important shift: AI-powered tools are accelerating the pace of vulnerability discovery, which means organizations need to be prepared to assess and respond to findings and changing situations faster than before. In addition to external factors, as organizations adopt AI—whether deploying foundation models, building agentic workflows, or using AI-powered services—how they implement their security controls must change as well. A strong security foundation is what makes confident AI adoption possible.

Here’s how SHIP helps:

Address foundational security gaps proactively

SHIP uses a data-driven methodology to identify opportunities to improve and optimize across 10 core security use cases: threat detection, cloud security posture management, application security testing, configuration management, access governance, vulnerability management, application protection, network security, encryption, and secrets management. The program includes a SHIP assessment to identify critical security findings related to your current security posture, so your team can build a prioritized roadmap for improvement tailored to your environment.

Establish the security baseline AI workloads require

Before you deploy your first model on Amazon Bedrock or build agentic workflows with Amazon Bedrock AgentCore, you need confidence that your underlying infrastructure follows security best practices. SHIP uses actual data from your environment to provide prescriptive, specific guidance rather than generic security recommendations. This is especially relevant as AI-driven vulnerability discovery tools become more widely available: organizations with strong baselines will be able to act on new findings quickly and effectively.

Build a mechanism for continuous security improvement

As AI capabilities evolve, organizations benefit from having a repeatable process to assess and strengthen their security posture over time. SHIP establishes the methodology and mechanisms for your team to continuously assess, prioritize, and improve. By building this operational capability, you’re strengthening your organization’s ability to adapt and contributing to broader industry resilience. As the cybersecurity community integrates AI into defense strategies, SHIP helps you maintain foundational best practices so you can adopt these innovations effectively and with confidence.

Getting started is straightforward

SHIP is available today, at no cost, to every AWS customer. Here’s how to get started:

  1. Talk to your AWS account team. Ask about scheduling a SHIP engagement, or request one directly on the SHIP page.
  2. Attend a SHIP Activation Day. AWS regularly hosts hands-on workshops where you can run the SHIP assessment with AWS Solutions Architects and start building your improvement plan.
  3. Explore the prescriptive guidance. Consult the AWS Well-Architected Framework – Security Lens for documentation, reference architectures, and implementation guides you can start using today.

Take the next step together

AWS is committed to being the most secure cloud, from our participation in Project Glasswing to the security embedded in every layer of our infrastructure. Security is a shared responsibility, and programs like SHIP give customers the tools, guidance, and support to strengthen their security foundations so they can build confidently, no matter what comes next.

Ready to improve your security posture? Contact your AWS account team to schedule a SHIP engagement, or visit the SHIP resources page to learn more.

Celeste Bishop

Celeste Bishop

Celeste is a Senior Security Specialist at AWS, based in Austin, Texas. Over the past five years, she has held a range of security-focused roles spanning field and product marketing, developer relations, and executive engagement. She partners closely with customers, security leaders, and field teams to help organizations operate securely in the cloud. Celeste holds a Bachelor’s in Economics from the University of Texas at Austin.

Top announcements of the What’s Next with AWS, 2026

Post Syndicated from AWS News Blog Team original https://aws.amazon.com/blogs/aws/top-announcements-of-the-whats-next-with-aws-2026/

Today at the What’s Next with AWS, Matt Garman, CEO of AWS, Colleen Aubrey, SVP Amazon Applied AI Solutions, Julia White, CMO of AWS, and OpenAI leaders discussed how they and their customers are changing how businesses operate with agents.

Here’s our roundup of the biggest announcements from the event:

Amazon Quick is an AI assistant for work that connects to all of them, learns what matters to you, and takes action on your behalf. Starting today, you can use the new desktop app, sign up for Free and Plus pricing plans, generate visual assets in the chat, and easily connect Quick to even more apps.

  • Quick’s new desktop app (Preview): You can create a personalized experience by staying connected to your local files, calendar, and communications without opening a browser.
  • New Free and Plus pricing plans for Quick: You can sign up within minutes using your personal email address or existing Google, Apple, Github, or Amazon credentials—no AWS account required.
  • Generate visual assets on the fly: Available today, Quick now lets you create polished documents, presentations, infographics, and images directly from the chat interface, no design skills or hours of formatting required.
  • Easily connect Quick to even more apps: Also available today, Quick is expanding its native integrations to include Google Workspace, Zoom, Airtable, Dropbox, and Microsoft Teams.

To learn more, visit the About Amazon News post.

Amazon Connect is expanding from a single product into a set of four agentic AI solutions designed to work within your existing workflows: Amazon Connect Decisions (supply chains), Talent (hiring), Customer (customer experience), and Health (health care).

  • Amazon Connect Decisions is a supply chain planning and intelligence solution that shifts teams from crisis management to proactive planning and decisioning. AI teammates, combining 30 years of Amazon operational science and 25+ specialized supply chain tools, adapt to your business, learn from your team, and continuously improve your operations.
  • Amazon Connect Talent (Preview) is an agentic AI hiring solution built for talent acquisition leaders managing scaled hiring. It delivers AI-led interviews, science-backed assessments, and consistent evaluation, helping recruiters hire high quality candidates faster while providing applicants with a flexible interview experience that reduces human preconceptions.
  • Amazon Connect Customer, previously known as Amazon Connect, delivers intelligent, personalized customer experiences across voice, chat, and digital channels. Amazon Connect Customer now offers new configuration capabilities that enable organizations to set up conversational AI in weeks, not months, and configure experiences without technical expertise.
  • Amazon Connect Health delivers agentic patient verification, appointment management, patient insights, ambient documentation, and medical coding — giving patients faster access to care, clinicians more time for care, and staff capacity for specialized work.

To learn more, visit the About Amazon News post.

AWS and OpenAI extended partnership
AWS and OpenAI are bringing the latest OpenAI models to Amazon Bedrock, launching Codex on Amazon Bedrock, and launching Amazon Bedrock Managed Agents, powered by OpenAI (all in limited preview), giving enterprises the frontier intelligence they want on the infrastructure they trust.

  • OpenAI models on Amazon Bedrock (Limited preview): The latest OpenAI models, including GPT-5.5 and GPT-5.4, will be available in preview on Amazon Bedrock. Use OpenAI’s frontier models through the same Bedrock APIs you already rely on, with unified security, governance, and cost controls. No additional infrastructure to configure, no new security model to learn.
  • Codex on Amazon Bedrock (Limited preview): You can access the OpenAI coding agent within the AWS environments where they already operate at scale. You can authenticate using their AWS credentials, process inference through Amazon Bedrock infrastructure, and apply Codex usage toward their AWS cloud commitments. Codex on Bedrock is available through the Bedrock API, starting with the Codex CLI, the Codex desktop app, and Visual Studio Code extension.
  • Amazon Bedrock Managed Agents, powered by OpenAI (Limited preview): Amazon Bedrock Managed Agents combines frontier AI models with trusted AWS infrastructure, enabling customers to quickly and easily build production-ready OpenAI-powered agents in the cloud. It is built with the OpenAI harness, which is engineered to unlock the full potential of OpenAI frontier models, delivering faster execution, sharper reasoning, and reliable steering of long-running tasks.

To learn more, visit the AWS What’s New post and About Amazon News post.

AWS Transform custom: Enterprise Code Modernization with the Learn-Scale-Improve Flywheel

Post Syndicated from Venugopalan Vasudevan original https://aws.amazon.com/blogs/devops/aws-transform-custom-enterprise-code-modernization-with-the-learn-scale-improve-flywheel/

Enterprise modernization has reached an inflection point. You can transform one repository easily. Existing tools, including AWS Transform custom, work well for individual repositories, and the process is understood. But what about 50 repositories? 100? 200? When you need to modernize at enterprise scale, transforming code is only part of the challenge. Coordinating people, capturing knowledge, and maintaining quality across your entire portfolio are also important.

In this post, we explore how AWS Transform custom’s bulk automation capabilities address the enterprise coordination problem through intelligent learning and scaled execution. You will see how one customer reduced end-to-end modernization timelines from 7-12 weeks to 2.5 weeks, delivering a 3-5x reduction in delivery time and 10-20x reduction in total effort hours. Most importantly, you will learn how to start your own transformation journey immediately.

The Coordination Problem at Enterprise Scale

Ask any enterprise architect about their last major modernization initiative, and you will hear familiar stories. As an example, an enterprise software company needed to migrate a large legacy codebase to a modern platform. Their projection: 12 weeks of intensive work coordinating across multiple teams.

The code transformation itself took days. The remaining weeks were consumed by the end-to-end activities surrounding it: orchestrating teams across time zones, ensuring consistent patterns across codebases with different histories, and managing dependencies so upstream changes did not break downstream systems. Teams tracked status through meetings and spreadsheets and captured tribal knowledge that existed only in senior developer heads.

This is the enterprise coordination problem. When you scale from one repository to hundreds, coordination overhead explodes. Each additional repository adds not just its own complexity, but new integration points, edge cases, and unanticipated coordination requirements.

The Hidden 70% Gap

In enterprise engagements, we have observed that code transformation represents approximately 30% of the modernization effort. The remaining 70% include things like test generation, validation, comprehensive documentation, business analysis, and organizational coordination across hundreds of moving pieces.

This gap explains why productivity gains from transformation tools rarely materialize. The tools handle code changes, but organizations still struggle with coordination, validation, and knowledge capture. The transformation is completed quickly, but the project takes months.

Here is what we see: traditional approaches fail at enterprise scale because they treat each repository as an independent challenge. Teams repeat work across codebases, make inconsistent decisions, and lose learnings when developers move to different projects. Organizational knowledge remains trapped in individual heads rather than becoming reusable assets.

A New Approach to Enterprise Modernization

AWS Transform custom takes a different approach to enterprise modernization. Rather than repeating the same operation hundreds of times, the service learns from every execution and applies that knowledge to improve future transformations.

The Learn-Scale-Improve Flywheel

The workflow follows a deliberate progression designed to maximize learning while minimizing risk. It begins with a focused learn pilot, scales through bulk automation, and improves through deliberate review, creating a flywheel where each cycle produces better results than the last (Figure 1).

Iterative transformation workflow with three stages: LEARN (interactive pilot, refine TD), SCALE (bulk execution, overnight processing), and IMPROVE (review and approve knowledge items). Arrows show the cycle: org knowledge captured flows from Learn to Scale, edge cases observed flow from Scale to Improve, and TD improves flows from Improve back to Learn.

Figure 1: Learn Scale and Improve Flywheel for AWS Transform custom transformation

Learn — You start with two to three representative repositories and execute transformations in interactive mode. You work directly with the AI agent, providing feedback on decisions and validating quality at each step. When the agent encounters ambiguity, it asks questions. You provide guidance, and the system captures that context. At the end of the pilot, you review the feedback and modify the transformation definition. The result is a transformation definition enhanced with your organizational knowledge, ready to scale.

Scale — You shift to non-interactive mode for bulk execution. The system processes dozens or hundreds of repositories overnight without manual intervention, applying patterns learned during the pilot. It validates transformations using your build and test commands and tracks progress across your portfolio in real time. What previously required weeks of team coordination happens overnight. During execution, the system captures observations: new edge cases, unexpected patterns, and optimization opportunities the pilot did not encounter.

Improve — After each round of bulk execution, you review the knowledge items the system captured during processing. These observations surface patterns and edge cases specific to repositories the pilot did not cover. You approve the valuable learnings, and your transformation definition improves for the next iteration. This review step ensures quality control. The system does not self-modify. Transformation owners decide which learnings get incorporated.

The Scale-Improve cycle repeats. Each round of bulk execution generates insights that make the next round more effective. Transformation success rates increase, manual intervention decreases, and edge case handling improves with every iteration.

This flywheel transforms how enterprises capture and share institutional knowledge. Transformation definitions are not automation scripts. They are organizational assets that encode how your company approaches specific modernization scenarios. When an architect defines a transformation strategy, that strategy becomes a reusable definition stored in your registry. When your team identifies best practices, those practices become embedded within the transformation definition and automatically apply across all repositories. Previously, when a senior developer left your team, that knowledge disappears with them. With AWS Transform custom, their expertise is captured in transformation definitions and knowledge items available to the entire organization. Individual expertise becomes an organizational capability.

An Enterprise Customer Modernization Case Study

These productivity gains are production outcomes, not theoretical projections. An enterprise software company needed to migrate a large volume of production-grade Control-M workflows to Apache Airflow, a modernization requiring both technical precision and consistency across a complex, interdependent codebase. Their estimate was 12 weeks of intensive coordination across multiple teams, with risk of inconsistency and integration failures.

Using AWS Transform custom, the company executed an iterative learn-scale-improve workflow. During the pilot phase, they ran interactive transformations on representative repositories, reviewed results, and refined transformation definitions. With each iteration, transformation definitions improved in edge case handling and accuracy. They then shifted to non-interactive bulk execution across their portfolio and completed the full migration in 2.5 weeks.

The validation achieved a 100% success rate across all workflows in scope. Edge case handling improved by 60% compared to the customer’s existing approach, and the transformed code demonstrated a 19% runtime performance improvement while meeting industry expert code quality standards. This proves that organizations can achieve both migration speed and production readiness, with 3-5x faster delivery timelines and 10-20x reduction in total effort hours compared to traditional approaches.

Get Started: Transform Your Repository Portfolio

AWS Transform custom bulk automation capabilities are available as a solution in this Github repo. Follow the learn-scale-improve workflow to begin your transformation journey.

Prerequisites

Before beginning, ensure you have:

  • An AWS account with AWS Transform custom access enabled
  • AWS CLI configured with appropriate credentials
  • Git installed on your local machine or CI/CD environment
  • IAM permissions for AWS Transform custom operations

Your Implementation Path

AWS Transform custom supports Java upgrades (e.g., 8 to 17, 17 to 21), Python migrations (e.g., 3.7 to 3.11), Node.js updates (e.g., 14 to 20), AWS SDK migrations (e.g., boto2 to boto3, SDK v1 to v2), and other transformations. Beyond these AWS-managed transformations, you can create custom transformation definitions for organization-specific standards, proprietary framework migrations, and architectural patterns unique to your environment.

AWS Transform custom integrates naturally into your existing development processes. The CLI connects with CI/CD pipelines like Jenkins, GitLab CI, or GitHub Actions. Transformations create code in local Git branches that flow through your standard code review and merge processes. The web interface provides centralized visibility for tracking progress across teams. Validation commands execute automatically during transformation, ensuring code builds successfully and tests pass before changes are considered complete. At the end of the transformation, if validation criteria fail, the transformation is marked as failed.

To accelerate your path to scaled execution, AWS provides an open-source sample repository that gives you a production-ready starting point for running transformations across multiple repositories and transformation definitions simultaneously. The aws-transform-custom-samples scaled execution repository includes scripts that orchestrate bulk execution, manage repository queuing, and handle status tracking across your portfolio. Rather than building orchestration from scratch, you clone the sample, configure it with your repository list and transformation definitions, and begin executing scaled transformations immediately.

Conclusion

Enterprise modernization at scale requires more than code transformation tools. The real challenges are coordination across teams, learning from execution, and capturing knowledge as organizational assets. AWS Transform custom learn-scale-improve workflow addresses these challenges through continual learning that improves quality with every execution, organizational knowledge capture that transforms tribal expertise into reusable assets, and bulk automation that scales consistently across hundreds of repositories. When the next critical security vulnerability requires framework updates across your repositories, or a new runtime version unlocks performance improvements, you respond in days rather than months — using transformation definitions you have already proven.

Real customers have reduced delivery timelines by 3-5x and total effort hours by 10-20x, compressing modernization from months to weeks. These are not aspirational goals. They are production results from organizations using AWS Transform custom today.

Begin Your Transformation Today

Follow the learn-scale-improve workflow on two to three representative repositories, refine your transformation definitions, then scale across your portfolio.
To dive deeper into AWS Transform custom bulk automation capabilities, explore these resources:

      • AWS Transform custom Documentation — Technical documentation covering all capabilities, API references, and integration guides: AWS Transform custom
      • Scaled Execution Sample Repository — Open-source scripts for running transformations across multiple repositories and transformation definitions: aws-transform-custom-samples
      • Transformation Registry — Discover AWS-managed transformations and create custom definitions: aws-transform-custom-samples

Contact your AWS account team or visit the AWS Transform custom documentation to begin your journey.


About the authors

meghan-author

Meghan Kothari

Meghan Kothari is a Senior Technical Product Manager with the Customer Experience and Business Trends team, where he partners with AWS leadership on strategic deep dives to discover evolving trends in agentic AI-driven application development and modernization. His background as a solutions architect and full-stack developer gives him a unique hands-on perspective to help shape the developer experience. 

Venu-author

Venugopalan Vasudevan

Venugopalan Vasudevan (Venu) is a Principal Specialist Solutions Architect at AWS, where he leads Agentic AI initiatives focused on AWS Transform. He helps customers adopt and scale AI-powered developer and modernization solutions to accelerate innovation and business outcomes.
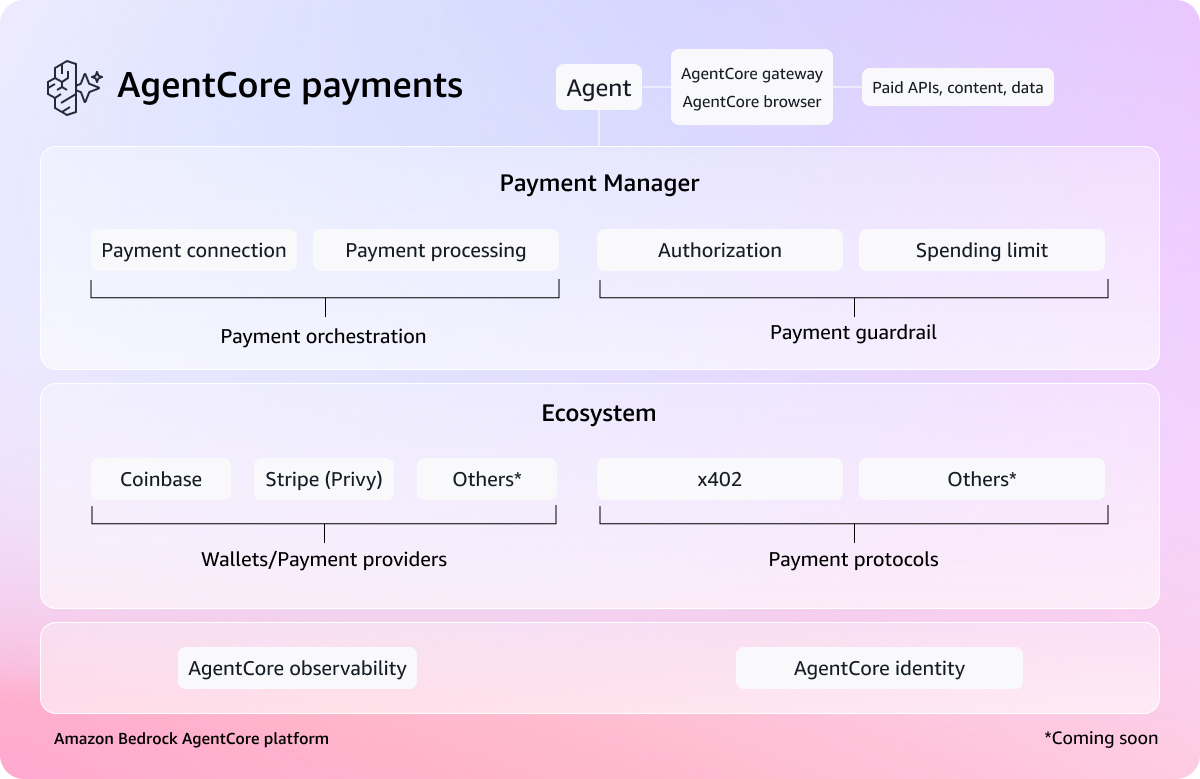
grilli-author

Rodney Grilli

Rodney Grilli is a Principal Technologist at AWS, specializing in product and code modernization using agentic AI services. He builds solutions that help customers modernize their product portfolios and accelerate their transformations into AI-Native Enterprises.

3 Reasons to Attend our Global Cybersecurity Summit if you’re Focused on AI, Threats, and CTEM

Post Syndicated from Emma Burdett original https://www.rapid7.com/blog/post/it-why-attend-global-cybersecurity-summit-ai-exposure-management-ctem

Security teams are dealing with a different kind of pressure now. It is not just the volume of alerts or the pace of attacks, but also the gap between what teams can see and what they can act on with confidence.

That gap shows up in different ways. Threats move across identity and cloud in ways that are difficult to track, exposure data exists but often sits disconnected from response, and AI is being introduced into workflows without a clear role in decision-making.

This year’s Rapid7 Global Cybersecurity Summit brings those threads together as part of the same operational solution.

1. You need a clearer view of how attacks actually unfold

A lot of detection strategies still assume attacks follow a clean path. In practice, they do not. They start in one place, move quickly, and often rely on small gaps rather than obvious failures.

Sessions like The Reality of Running a SOC in 2026 break this down in detail, looking at how attacks begin with things like identity misuse or cloud misconfiguration, then evolve as defenders try to keep up. That matters because it changes how detection should be designed. Coverage alone is not enough if teams do not have the context created by strong exposure management to interpret what they are seeing.

That same idea carries into Inside the Modern SOC, where a real investigation is followed from first alert to outcome. It is a useful reminder that detection is only part of the problem.Deciding how to respond, and doing it quickly, is the critical next step.

2. Exposure only matters if it connects to action

Most teams already have some form of exposure management in place. The challenge is making it useful. A long list of vulnerabilities does not help much if it is not tied to how risk actually shows up in the environment.

Sessions like Beyond the Vulnerability List and From Cloud Exposure to Runtime Attack focus on that connection. They look at how exposures turn into active threats, often before any alert is triggered, and how teams can use that information to prioritize earlier.

Here’s the part people miss. Exposure is not just about knowing what is wrong. It is about understanding what matters now, based on how the environment is being used and how attackers are likely to move through it.

3. AI is only useful if it improves decisions

AI is already part of most security conversations, but the reality is nuanced. In some cases it helps reduce noise and speed up investigations. In others, it creates new questions around trust and transparency.

The AI Dilemma: Automating Defense Without Surrendering Judgment tackles this directly. It looks at where AI is helping in real SOC workflows, where it can get in the way, and why explainability matters if teams are going to rely on it. The discussion is grounded in how analysts actually work, not just what the technology promises.

There is also a broader point here. Attackers are using AI as well, which means the balance between speed and accuracy is becoming more important on both sides.

Join the conversation

Across these sessions, the common doesn’t stem from any single technology. It is how teams connect signals, context, and decisions in a way that holds up under pressure, which shows up in how threats are understood, how exposure is prioritized, and how AI is applied. It is also why the summit is structured the way it is, moving from shared context on day one into more focused, role-based sessions on day two.

More sessions and speakers will be added in the coming weeks, but the direction is already clear. Security operations are shifting toward earlier decisions, better prioritization, and fewer assumptions.

If your work touches AI, threat detection, or exposure management, this is where those conversations start to come together.

Join us May 12–13 and see how teams are approaching it in practice.

Register now.

From Bulk Export to AI-ready Security Workflows: Introducing Rapid7’s Open-Source MCP Server and Agent Skill

Post Syndicated from Michael Chroney original https://www.rapid7.com/blog/post/em-bulk-export-ai-ready-security-workflows-open-source-mcp-server-agent-skill

A new open-source bridge helps customers connect Rapid7 vulnerability data to AI agents, assistants and custom workflows with more flexibility, control, and faster access to insight.

Security teams want more from their data than APIs and one-off reports.

They want to ask better questions, move faster, and bring security context into the workflows they are already building. That’s especially true as more organizations experiment with private AI assistants, internal copilots, and LLM-powered automation. Part of this experimentation is, of course, attempting to lower the pressure on teams that have to figure out how to prioritize the sheer number of actionable vulnerabilities efforts like Project Glasswing are quickly becoming hyper-skilled at spotting.     

That’s why Rapid7 is introducing a free, open-source MCP Server and Agent Skill for Bulk Export. Bulk export is a highly efficient way to access all your Rapid7 data; no more paging APIs, no more verbose output. Bulk Export creates a local offline replica of your data the LLM can efficiently and quickly interrogate, reducing token cost and time to answer questions.

This new MCP and Agent Skill gives customers a standardized way to connect Rapid7 vulnerability and exposure data to AI assistants and custom AI workflows. Built as an open-source bridge, it helps customers bring their Rapid7 data into the tools and experiences that work best for their teams.

image3.png

Why this matters now

Security teams are no longer just buying tools. They’re connecting systems, shaping workflows, and testing how AI can help analysts, IT teams, and leaders get to answers faster. For many teams, the path from raw security data to usable AI context is still manual. It often means exporting data, building wrappers, shaping queries, and managing custom integrations.

Rather than leave every team to solve that challenge from scratch, we wanted to provide a stronger foundation that is flexible, practical, and easy to extend over time. With projects like Metasploit and Velociraptor, Rapid7 is committed to Open Source, and by sharing with the broader community we hope to accelerate velocity and ensure we’re able to incorporate more use cases and fixes. These processes also give customers full visibility of the code running and tools used, ensuring data privacy and allowing the user to do with their data what they please.  

What MCP does

Model Context Protocol, or MCP, is an emerging standard for helping AI systems interact with external data and tools in a structured way.

In practical terms, it gives AI assistants a cleaner way to ask questions, retrieve data, and work with systems beyond the model itself. For customers, that means less custom glue code and a more consistent way to use security telemetry in AI-driven workflows.

That matters because many security reporting and analysis workflows still assume a high technical bar. Answering a simple question can require custom queries, SQL knowledge, or dashboard work. But the people who need those answers aren’t always security specialists. They may be IT partners, compliance stakeholders, or executives who want clarity but might not need to understand the underlying query logic.

The MCP server helps lower that barrier: Instead of starting with raw exports and working backward, teams can start with the question they need answered.

The bigger picture: MCP and CTEM

This approach also aligns with the broader shift toward continuous threat exposure management, or CTEM. 

CTEM is about helping teams move beyond point-in-time findings toward a more continuous, contextual understanding of risk. That requires security data that can be accessed, connected, and used across the workflows teams rely on. 

Bulk Export helps make that possible by giving customers more flexibility in how they use Rapid7 data. The open-source MCP server makes it easier to bring that data into AI-assisted and custom workflows.

image1.png

⠀

That can support more continuous exposure management workflows by making it easier for teams to triage vulnerability and exposure data. For example, an analyst facing a large queue of new vulnerabilities could use LLM assistance to quickly narrow in on the findings most likely to need attention first. Instead of manually working through exports and queries, they could ask natural-language questions to surface the exposures tied to critical assets, unresolved remediation work, or other signals available in the data.

From data portability to AI-ready interoperability

Bulk Export was already an important step toward giving customers more control over their data. It made it easier to extract and use security telemetry in external tools and analytics environments.

The open-source MCP server builds on that foundation: Instead of using exported data only for dashboards or custom reporting, customers can now use that same data in AI-native experiences. That includes internal assistants, private copilots, workflow automation, and natural-language exploration of vulnerability and exposure data. This makes existing security data easier to use in the environments customers are already investing in.

How it works

At a high level, the architecture is straightforward. Using the Agent Skill, your LLM runs the MCP server locally and automatically prepares the environment by performing the bulk export and loading the data into a local file store. The Agent Skill provides the schemas and knowledge, with the MCP providing the tools to access this data. The LLM then will answer any question by querying, summarizing, and synthesising data locally – an extremely fast and simple process that’s for the LLM. 

Depending on the data a customer exports, answers can include vulnerability records, asset data, remediated vulnerabilities, and policy-related results.

The point here isn’t just that a model can access the data, it’s that an open-source layer helps customers inspect, adapt, and extend over time, empowering teams to control how that connection works in their own environment. 

What customers can do with it

This opens the door to practical use cases, including:

  • Using LLM assistance to triage vulnerability data faster 

  • Asking natural-language questions to spot exposure and remediation trends

  • Investigating which assets are tied to the most urgent vulnerabilities

  • Understanding what changed over time without manual analysis

  • Exploring policy failures without building manual queries

  • Feeding Rapid7 telemetry into private AI assistants and internal workflows

  • Making reporting more accessible for non-technical stakeholders

image2.png

⠀

For teams already trying to operationalize AI, this creates a lower-friction path. Instead of building every integration from the ground up, they can start with a reusable bridge and focus on the workflows they want to enable.

A better path from data to action

Security data only creates value when teams can use it. For many organizations, turning raw telemetry into timely answers is still harder than it should be. Analysts need speed. Leaders need clarity. Builders need flexibility. And more customers want security data that works inside the tools and workflows they already rely on.

The open-source MCP server for Bulk Export is designed to help make that possible.

Bulk Export helps customers take control of their data. This is the next step: helping them put that data to work in AI-ready security workflows.

Ready to explore it for yourself? Visit the Rapid7 Bulk Export MCP Server project on GitHub to learn more and get started.

Project Glasswing and the Next Challenge for Defenders: Turning Faster Discovery into Faster Action

Post Syndicated from Craig Adams original https://www.rapid7.com/blog/post/ai-project-glasswing-challenge-faster-discovery-and-action

Anthropic’s Project Glasswing has sparked plenty of discussion about what AI might soon do for vulnerability discovery, but the more useful question for most security teams is how to prepare for, and more importantly seize the opportunity of, what comes next.

 As we wrote in our earlier blog, What Project Glasswing Means for Security Leaders, AI is becoming more capable of finding software flaws. The pressure that follows lands on the teams responsible for deciding what matters, validating risk, assigning ownership, and getting remediation moving across environments that were already hard to manage. We believe that the organizations that will benefit most from the next wave of AI will be the ones that understand their environment well enough to use these emerging AI models with intent, rather than layering them onto immature processes and hoping that speed alone will solve the backlog.

What this moment means for security teams

The number of publicly tracked software vulnerabilities has broken records almost every year over the last decade, while supply chain risk has continued to rise. Most teams were already feeling the strain of more findings than they could process cleanly. The Common Vulnerabilities and Exposures (CVE) program, the standard system for identifying and tracking known vulnerabilities, recorded 48,185 disclosures in 2025, a 20% increase over 2024, with roughly 40% of those disclosed vulnerabilities rated high or critical. 

The pace in 2026 was already working out to hundreds of new CVEs per day when those figures were cited. That tells you something important about the current environment: the challenge has not necessarily been  a lack of findings, but instead converting a growing stream of findings into measurable risk reduction.

The reality is that very few organizations are going to hand a model free rein over their most sensitive environments the minute those capabilities become more widely available. Trust will be built in stages: early adoption is much more likely to focus on backlog reduction, triage support, patch testing, and repetitive lower-tier remediation work that consumes time without carrying the same level of operational risk as the most critical systems in the business. That is a more realistic starting point, and it leads to a more useful question. Before teams apply AI more broadly, they need to understand their environment well enough to use it intentionally.

Establish the foundation before layering in AI

The promise from Project Glasswing and almost every other AI-powered security initiative is quite similar: leverage AI to identify patterns, summarize risk, suggest fixes, and speed up repetitive work. Regardless of technology, success  still depends on how well an organization understands its environment, the context around each finding, and the process used to act on it. 

A model can generate more output than a team ever could on its own, but that output becomes noise if the organization cannot answer basic questions about scope, ownership, criticality, and exposure. Teams need a clear, continuously updated picture of the environment before they can decide where AI should be applied, what should remain human-led, and which parts of the backlog are safe to push through more automated workflows.

The AI landscape is already shifting fast, and it will keep shifting, which is why this moment should prompt a more preemptive and resilient strategy rather than another round of tooling hype. Chasing each new capability as it arrives will inevitably force teams to keep reorganizing around the latest announcement. A stronger path is to get the foundation right first – understand the environment, the attack paths, and the assets that matter most; but most importantly, establishing the process and the people behind making these decisions. Then use AI where it meaningfully improves speed, consistency, and focus.

Why Attack Surface Management should be part of that foundation

A strong foundation starts with visibility. Security teams need a live picture of what exists in the environment, what is exposed, how assets connect to one another, and which systems carry the greatest business impact if something goes wrong. That is where Attack Surface Management becomes central. Rapid7’s approach through Surface Command is built around a continuous view of the attack surface across the digital estate, which helps teams understand where exposures sit and how they relate to internet-facing, business-critical, or otherwise high-impact systems.

That matters for AI adoption just as much as it matters for day-to-day security operations. Teams cannot apply AI strategically if they are guessing about which parts of the environment are lower priority, which assets belong to which owners, or where a newly disclosed flaw could create real business risk. A better view of the attack surface gives organizations the context they need to segment the problem properly. That makes it far easier to start with the right use cases, whether that is backlog reduction in lower-impact systems, targeted prioritization of exposed assets, or faster triage where the risk picture is already well understood.

Ownership is part of that foundation too. Remediation slows down when no one can quickly identify who owns the affected application, environment, or workflow. Security teams already lose time there today, and AI will only make that bottleneck more visible if it starts surfacing issues faster than organizations can assign them. Attack Surface Management helps turn that ambiguity into something more actionable by tying exposure to environment context and likely ownership.

How Vulnerability and Exposure Management turns visibility into action

Once the environment is understood, teams still need a way to move from findings to outcomes. That is where Vulnerability and Exposure Management becomes the operating layer that keeps the work grounded.

The biggest value here is not simply collecting more vulnerability data. It is targeted prioritization and validation. When a disclosure lands, teams need to know whether the issue affects an exposed asset, whether there is evidence of exploitation or attacker interest, whether the impacted system is business-critical, and whether existing controls already reduce some of the risk. That is the kind of context that helps organizations decide what deserves immediate attention and what can be handled through a normal remediation cycle.

This is where artificial intelligence can help move remediation forward faster. Instead of asking teams to manually connect exploit signals, asset criticality, and vulnerability intelligence on their own, AI can distill that context directly in the remediation workflow. That makes it easier to understand why an issue matters, what the likely impact is, and what to do next, which shortens the gap between discovery and a confident decision on how to respond.

We expect most organizations to use AI to assist with, or in some cases take over, lower-tier triage, backlog cleanup, summary generation, and patch support in areas where the workflow is already established and the blast radius is more manageable. Human experts still stay closest to the most critical business logic, the most sensitive environments, and the most complex remediation paths. That is a practical adoption model, and it only works when the organization already has enough structure in place to know where those boundaries are.

Curated vulnerability intelligence changes the quality of decisions

That kind of deliberate adoption only works when teams can make better decisions, faster. Security teams need more than severity scores and a long list of CVEs. They need enough context to understand what matters, what can wait, and where action will reduce real risk fastest. As Rapid7 outlined in The Power of Curated Vulnerability Intelligence, the goal is to identify the vulnerabilities that actually matter and give teams enough context to act with confidence.

That intelligence provides a form of validation that most teams need badly as disclosure volume rises. It helps answer whether a finding is tied to active attacker interest, whether proof-of-concept activity is public, whether the asset is exposed, and whether delaying a patch creates unacceptable risk. It also supports the decisions that happen in the gap between discovery and full remediation. When a patch is delayed because of change controls, testing constraints, or lack of a vendor fix, teams still need to reduce exposure. Curated intelligence helps them decide whether to use segmentation, access restrictions, configuration changes, added monitoring, or virtual patching while the longer-term fix is being worked through.

That is one of the clearest ways Rapid7 helps customers move from data to outcomes. Intelligence is fused into the workflow so teams can prioritize with more precision and validate their actions against real threat context, not just generalized scores.

How runtime and remediation fit into the broader AI story

There is another part of this story that matters as organizations think more seriously about AI-driven security operations. As AI shapes the way teams handle exposures earlier in the lifecycle, context of application at runtime matters more too.

To make that foundation complete, organizations need to look beyond static posture and bring runtime validation into the picture. When teams can identify which vulnerabilities and misconfigurations are actively exploitable in production, and map sensitive data and identity access to real-world attack paths, they get a much clearer view of actual risk. Security teams need to understand what is vulnerable, how systems behave when live, and where unusual activity may suggest a problem is moving toward exploitation. With that runtime context in place, teams can spend less time chasing theoretical vulnerabilities and more time focusing on the exposures that are actively creating risk in live environments. 

That connection between exposure, intelligence, remediation, and runtime behavior is where AI starts to become genuinely useful rather than simply impressive. It supports a more intentional model of security decision-making, one that narrows the gap between what is found, what matters, and what happens next.

What security leaders should do now

This is a good time for security leaders to step back and ask a more disciplined set of questions.

  • Do we understand our environment well enough to direct AI toward the right problems? 

  • Can we clearly separate higher-risk, higher-impact assets from the parts of the backlog that are mostly operational drag? 

  • Is threat intelligence embedded in how we interpret findings, or are we still depending too heavily on raw severity? 

  • Can we identify ownership fast enough for AI-assisted triage to result in meaningful action? 

  • Are compensating controls part of the plan when remediation cannot happen immediately?

Those questions shape the quality of everything that follows.

Glasswing creates a real opportunity for security teams that are ready to use AI with more intention. AI can move work forward faster, reduce manual drag, and absorb classes of issues that currently consume time without improving outcomes. The teams that benefit most will not be the ones that rush to apply new models everywhere. They will be the ones that understand their environment, have a clear view of their attack surface, have mature enough workflows to apply AI where it makes sense, and can measure whether the actions taken actually reduced exposure.

Rapid7’s approach to building resilience is grounded in those same needs. Attack Surface Management provides the environmental foundation, Vulnerability Management drives prioritization and action, curated vulnerability intelligence strengthens validation and decision-making, AI-generated remediation insights compress the time from discovery to the next step, and runtime security adds context where live behavior matters. Together, those pieces help customers build a security program that is ready for AI rather than constantly reacting to it.

Introducing Anthropic’s Claude Opus 4.7 model in Amazon Bedrock

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/introducing-anthropics-claude-opus-4-7-model-in-amazon-bedrock/

Today, we’re announcing Claude Opus 4.7 in Amazon Bedrock, Anthropic’s most intelligent Opus model for advancing performance across coding, long-running agents, and professional work.

Claude Opus 4.7 is powered by Amazon Bedrock’s next generation inference engine, delivering enterprise-grade infrastructure for production workloads. Bedrock’s new inference engine has brand-new scheduling and scaling logic which dynamically allocates capacity to requests, improving availability particularly for steady-state workloads while making room for rapidly scaling services. It provides zero operator access—meaning customer prompts and responses are never visible to Anthropic or AWS operators—keeping sensitive data private.

According to Anthropic, Claude Opus 4.7 model provides improvements across the workflows that teams run in production such as agentic coding, knowledge work, visual understanding,long-running tasks. Opus 4.7 works better through ambiguity, is more thorough in its problem solving, and follows instructions more precisely.

  • Agentic coding: The model extends Opus 4.6’s lead in agentic coding, with stronger performance on long-horizon autonomy, systems engineering, and complex code reasoning tasks. According to Anthropic, the model records high-performance scores with 64.3% on SWE-bench Pro, 87.6% on SWE-bench Verified, and 69.4% on Terminal-Bench 2.0.
  • Knowledge work: The model advances professional knowledge work, with stronger performance on document creation, financial analysis, and multi-step research workflows. The model reasons through underspecified requests, making sensible assumptions and stating them clearly, and self-verifies its output to improve quality on the first step. According to Anthropic, the model reaches 64.4% on Finance Agent v1.1.
  • Long-running tasks: The model stays on track over longer horizons, with stronger performance over its full 1M token context window as it reasons through ambiguity and self-verifies its output.
  • Vision: the model adds high-resolution image support, improving accuracy on charts, dense documents, and screen UIs where fine detail matters.

The model is an upgrade from Opus 4.6 but may require prompting changes and harness tweaks to get the most out of the model. To learn more, visit Anthropic’s prompting guide.

Claude Opus 4.7 model in action
You can get started with Claude Opus 4.7 model in Amazon Bedrock console. Choose Playground under Test menu and choose Claude Opus 4.7 when you select model. Now, you can test your complex coding prompt with the model.

I run the following prompt example about technical architecture decision:
Design a distributed architecture on AWS in Python that should support 100k requests per second across multiple geographic regions.

You can also access the model programmatically using the Anthropic Messages API to call the bedrock-runtime through Anthropic SDK or bedrock-mantle endpoints, or keep using the Invoke and Converse API on bedrock-runtime through the AWS Command Line Interface (AWS CLI) and AWS SDK.

To get started with making your first API call to Amazon Bedrock in minutes, choose Quickstart in the left navigation pane in the console. After choosing your use case, you can generate a short term API key to authenticate your requests as testing purpose.

When you choose the API method such as the OpenAI-compatible Responses API, you can get sample codes to run your prompt to make your inference request using the model.


To invoke the model through the Anthropic Claude Messages API, you can proceed as follows using anthropic[bedrock] SDK package for a streamlined experience:

from anthropic import AnthropicBedrockMantle
# Initialize the Bedrock Mantle client (uses SigV4 auth automatically)
mantle_client = AnthropicBedrockMantle(aws_region=REGION)
# Create a message using the Messages API
message = mantle_client.messages.create(
    model="anthropic.claude-opus-4-7",
    max_tokens=2048,
    messages=[ 
	    {"role": "user", "content": "Design a distributed architecture on AWS in Python that should support 100k requests per second across multiple geographic regions"}
    ]
)
print(message.content[0].text)

You can also run the following command to invoke the model directly to bedrock-runtime endpoint using the AWS CLI and the Invoke API:

aws bedrock-runtime invoke-model \ 
 --model-id anthropic.claude-opus-4-7 \ 
 --region us-east-1 \ 
 --body '{"messages": [{"role": "user", "content": "Design a distributed architecture on AWS in Python that should support 100k requests per second across multiple geographic regions."}], "max_tokens": 512, "temperature": 0.5, "top_p": 0.9}' \ 
 --cli-binary-format raw-in-base64-out \ 
invoke-model-output.txt

For more intelligent reasoning capability, you can use Adaptive thinking with Claude Opus 4.7, which lets Claude dynamically allocate thinking token budgets based on the complexity of each request.

To learn more, visit the Anthropic Claude Messages API and check out code examples for multiple use cases and a variety of programming languages.

Things to know
Let me share some important technical details that I think you’ll find useful.

  • Choosing APIs: You can choose from a variety of Bedrock APIs for model inference, as well as the Anthropic Messages API. The Bedrock-native Converse API supports multi-turn conversations and Guardrails integration. The Invoke API provides direct model invocation and lowest-level control.
  • Scaling and capacity: Bedrock’s new inference engine is designed to rapidly provision and serve capacity across many different models. When accepting requests, we prioritize keeping steady state workloads running, and ramp usage and capacity rapidly in response to changes in demand. During periods of high demand, requests are queued, rather than rejected. Up to 10,000 requests per minute (RPM) per account per Region are available immediately, with more available upon request.

Now available
Anthropic’s Claude Opus 4.7 model is available today in the US East (N. Virginia), Asia Pacific (Tokyo), Europe (Ireland), and Europe (Stockholm) Regions; check the full list of Regions for future updates. To learn more, visit the Claude by Anthropic in Amazon Bedrock page and the Amazon Bedrock pricing page.

Give Anthropic’s Claude Opus 4.7 a try in the Amazon Bedrock console today and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

— Channy

Turning Log Lines into Answers: Instant Clarity for SOC Teams

Post Syndicated from Sean O'Brien original https://www.rapid7.com/blog/post/dr-log-lines-into-answers-instant-soc-clarity-ai

Security teams are flooded with logs, yet every alert demands fast, accurate context. In Verizon’s 2025 Data Breach Investigations Report [1], they analyzed 22,052 security incidents, of which 12,195 (55%) were confirmed breaches, underscoring how much activity teams must sift through to find what matters.

In practice, that means dozens of investigations per shift, each requiring fast judgment with incomplete context. A 2024 SANS survey shows that SOC teams report alert volume, limited context, and lack of automation continue to slow investigation and response [2].

Speed suffers. So does consistency.

Turn raw logs into a clear narrative

AI-Powered Log Summary in Rapid7 Incident Command transforms raw log data into a clear, concise narrative directly within the investigation workflow. Analysts see what happened, why it matters, and what to do next in seconds, not minutes.

Instead of decoding logs line by line, analysts get:

  • Instant identification of who initiated the activity.

  • Fast understanding of exactly which actions occurred.

  • Clarity into when and where events unfolded.

  • Connectivity into why that behavior matters.

Analysts stay grounded in the original data, but they no longer have to fight through it to find answers. The summary provides immediate orientation and focus, keeping their focus on what to do next.

Built for real SOC workflows

AI-Powered-Log-Summary-Endpoint-Activity-Detail.png
Figure 1: AI-Powered Log Summary Endpoint Activity Detail

⠀

AI-Powered Log Summary is embedded directly into the log search workflow. No pivoting, and no context switching. With a single action, analysts generate a contextual summary tailored to their results in seconds. That means faster investigations without breaking flow.

Summaries can be shared with teammates or leadership to communicate findings quickly, without rewriting technical details into plain language. Everyone stays aligned on what happened and what comes next.

AI integration in action

Rapid7 leverages the best available technology to protect our customers’ attack surfaces. Our mission drives us to keep abreast of the latest AI advancements to deliver optimal value to customers while effectively managing the inherent risks of the technology. Integrating AI into our core processes enhances our operational security and underscores our commitment to ethical innovation. 

At Rapid7, we are dedicated to leading responsibly in the AI space, ensuring that our technological advancements positively contribute to our customers, company, and society. Read more about how our TRiSM (Trust, Risk, and Security Management) is a foundational strategy that guides us in navigating the intricate landscape of AI with confidence and security.

Less noise, more impact

By reducing time spent parsing logs, teams can focus on what matters: containment, remediation, and proactive threat hunting.

AI-Powered-Log-Summary-Web-Proxy-Detail.png
Figure 2: AI-Powered Log Summary Web Proxy Detail

⠀

This brings analysts:

  • Faster triage and investigations.

  • More consistent analysis across shifts.

  • Lower cognitive load during high-volume periods.

  • Clear communication to stakeholders.

Rapid7 is at the vanguard of integrating AI into its products to accelerate outcomes for our customers, with a particular focus on amplifying analyst impact and bringing speed and clarity to SOC operations throughout the threat detection and response lifecycle. 

That is how modern SOC teams move faster. Visit the Incident Command page for more information.

⠀

[1] Verizon 2025 DBIR

[2] SANS 2024 SOC Survey

What Project Glasswing Means for Security Leaders

Post Syndicated from Douglas McKee, Director, Vulnerability Intelligence original https://www.rapid7.com/blog/post/ai-what-project-glasswing-means-for-security-leaders

Anthropic’s Project Glasswing matters because it offers an early look at how quickly software flaws may soon be found, validated, and potentially turned into viable attack paths, even if that capability is currently limited to a closed partner program. Anthropic says its restricted Claude Mythos Preview model has already identified thousands of high-severity vulnerabilities, including flaws in major operating systems and browsers, and in some cases developed related exploits autonomously.

Some early coverage has emphasized the risks and need for restraint in deploying capabilities like this, and for most organizations, it won’t immediately change day-to-day security operations. What it does offer is a signal of where the industry may be heading: a future where discovery moves faster, and where the pressure shifts to everything that follows, including prioritization, remediation, validation, and response. Glasswing feels less like the storm itself and more like the first sign that the radar is getting better faster than the emergency plan. How well can we handle what comes next?

What is Project Glasswing?

Project Glasswing is Anthropic’s new defensive security initiative built around Claude Mythos Preview, a model the company is not releasing publicly because of its cyber capabilities. Anthropic says the preview is being provided to a limited set of organizations, including AWS, Apple, Broadcom, Cisco, CrowdStrike, Google, JPMorganChase, the Linux Foundation, Microsoft, Nvidia, and Palo Alto Networks, with access also extended to more than 40 additional organizations. Anthropic has also committed up to $100 million in usage credits and additional support for open-source security work. 

That makes this more than another AI feature release. Anthropic is effectively signaling two things at once. First, there is a meaningful backlog of serious, undisclosed vulnerabilities still out there. Second, capabilities like this are sensitive enough that broad public release would be irresponsible right now. For security leaders, the message is not that AI replaces human researchers. It is that AI is becoming materially more useful in vulnerability research, and defenders should be thinking now about how they will handle what comes next.

Why this matters to vulnerability management

It would be easy to read this as a story about faster vulnerability discovery alone. That misses the more important point. If Anthropic’s claims are directionally right, the immediate pressure does not land on discovery alone. It lands on everything downstream of discovery: asset context, exploitability analysis, ownership, compensating controls, patching, exception handling, validation, and detection coverage. In other words, the harder part of security becomes more obvious.

That matters because most enterprise programs do not struggle to generate findings. They struggle to decide which findings matter first, who should act, what can wait, and whether remediation actually reduced exposure. If AI pushes vulnerability discovery into a new gear, weak operating models will feel that pressure first. Backlogs get bigger. Teams drown in queues. Fix rates do not keep pace. Risk stays put. That is not a model problem. It is an execution problem. 

This is why security leaders should be careful with the framing. The headline is not “AI found bugs, therefore security improves.” The headline is that the bottleneck may be moving downstream even faster than expected. That raises the value of programs that connect exposure management, remediation, and runtime defense instead of treating them as separate activities. 

What Anthropic’s examples really tell us

Some of the reported examples are striking. Anthropic and media reports say Mythos Preview found a 27-year-old OpenBSD vulnerability, a 16-year-old FFmpeg flaw that reportedly evaded millions of automated test executions, and multiple Linux kernel vulnerabilities that could be chained together. Anthropic has also said the model reproduced vulnerabilities and built proof-of-concept exploits at a high success rate in testing. Even if individual examples get debated over time, the pattern is the important part. The model appears to compress several human steps into one workflow, from discovery to validation to exploit construction. 

Security has seen faster discovery before. Fuzzing changed the game. Better automation changed the game. Large-scale bug bounty operations changed the game. What is different here is the combination of reasoning, coding, persistence, and iteration inside a single model loop. If that loop becomes reliable, then defender workflows built for human-speed intake and triage will come under more strain. That does not make coordinated disclosure obsolete. It makes today’s processes look slow.

What CISOs should ask right now

CISOs do not need to decide this week whether Anthropic’s model changes the entire market. They do need to ask a more practical question: if my environment starts surfacing materially more vulnerabilities tomorrow, what happens next?

For many organizations, that answer is uncomfortable. Findings land in multiple tools. Asset inventory is incomplete. Internet exposure is only partly understood. Ownership is fragmented. Patch cycles are slow. Exceptions pile up. Security teams cannot easily prove that a fix changed reachable risk in the real environment.

That is where this news becomes relevant. AI-driven discovery does not reduce the need for an exposure-led security model. It increases it. The organizations that benefit most will not be the ones with the biggest pile of findings. They will be the ones that can connect those findings to business-critical assets, internet exposure, identity paths, existing detections, remediation workflows, and validation. 

A good board-level translation is that faster discovery only has value if the organization can prioritize effectively, remediate quickly, and prove that the fix reduced real exposure. Otherwise, the result is more volume and more noise.

What engineers should take away from Project Glasswing

For engineers, this announcement is less a reason to either celebrate or dismiss the technology than it is a sign that defensive research workflows may change quickly if capabilities like this spread more broadly. Today, Glasswing is still limited to a small group of trusted partners, so this is not yet a shift most engineering teams will feel directly in their daily work. What it does offer is an early look at where software security may be heading.

AI-assisted discovery is likely to become more common across secure development, code review, infrastructure testing, and open-source maintenance. That creates real opportunities. Models can help explore deep code paths faster, challenge assumptions earlier, improve reproduction, and generate more detailed reports than many conventional workflows produce today.

The harder question is what comes next. If AI can generate more findings and more exploit hypotheses, engineering teams will need stronger intake, validation, and prioritization discipline, not less. Triage quality, deduplication, severity context, reproducibility, and ownership all become more important as discovery speeds up. Many maintainers and internal product security teams already struggle with volume, and machine-generated reporting could make that problem worse if workflows do not mature alongside the tooling.

At the same time, that is only one side of the equation. If models can help find bugs faster, they may also help defenders confirm impact, suggest code changes, support patch development, and reduce some of the manual effort that slows remediation today. In the longer run, the same AI shift that increases pressure on defenders may also help them absorb some of that pressure. The real issue is not whether AI adds more findings. It is whether teams can use it to shorten the full path from discovery to decision to verified fix.

The best engineering response, then, is not to argue about whether these models are impressive. It is to improve the operating path around them. Can the team confirm impact quickly, tie a flaw to reachable attack surface, deploy a patch or control change, and verify that exposure is actually reduced in production? If that chain does not improve, faster discovery alone will not deliver much value.

What this means for the next phase of security

Anthropic’s decision to restrict access is understandable, but it also underscores a harder truth – capabilities like this rarely stay contained for long. Whether through competitors, open customization, or less restrained releases, the broader industry should assume similar models will become more widely available in the near term. For most organizations, this is not a market-wide operational shift today. It is a warning of what may be closer than it appears.

That signal arrives at a time when many security operations teams are already under strain. Most can investigate only a fraction of the alerts and exposures their environments generate, which keeps them in reactive mode, manually triaging high-priority signals across fragmented telemetry while scale and consistency remain difficult to achieve. Many promises of AI super-productivity have not yet translated into day-to-day operational relief. That is part of what makes Glasswing worth paying attention to. It points to a future where discovery may improve faster than most response models do.

It also points to an opportunity. If AI can compress parts of vulnerability research, the same broader class of capabilities may eventually help defenders improve prioritization, investigation, remediation, and validation as well. That is where the next phase of security is likely to be decided. Not in whether organizations can generate more findings, but in whether they can use AI to make response workflows faster, more consistent, and more precise.

From our perspective, that raises the operational bar for defenders. If discovery gets faster, organizations will need to shorten time to detect, accelerate time to patch, and manage vulnerability backlogs with far more urgency than they do today. That starts with a threat-led view of the environment. Teams need to understand which weaknesses are most exposed, most exploitable, and most likely to matter in real attack paths so they can prioritize action based on actual risk, not just queue depth.

That is the practical lesson from Glasswing. It feels less like the storm itself and more like the first sign that the radar is getting better faster than the emergency plan. For most organizations, the announcement does not change the queue tomorrow morning. What it does change is the urgency of preparing for a future in which discovery, triage, and response may all begin moving at a very different pace.

Building AI defenses at scale: Before the threats emerge

Post Syndicated from Amy Herzog original https://aws.amazon.com/blogs/security/building-ai-defenses-at-scale-before-the-threats-emerge/

At AWS, we’ve spent decades developing processes and tools that enable us to defend millions of customers simultaneously, wherever they operate around the world. Every day, our security and threat intelligence teams are doing work with AI and automation that most people never see. Our AI-powered log analysis system has reduced the time SecOps engineers spend analyzing security logs from an average of six hours to just seven minutes, a 50x productivity increase that lets us detect and respond to threats faster than ever. Across AWS, we analyze over 400 trillion network flows per day to detect patterns that signal emerging threats. In 2025 alone, we blocked over 300 million attempts to maliciously encrypt customer files hosted on Amazon S3.

What we learn protecting one customer helps protect all customers. At this scale, every threat we see makes our defenses stronger for everyone, and AI is already central to how we do it.

A new class of AI for cybersecurity

Today, Anthropic announced Project Glasswing, a cybersecurity initiative designed to secure the world’s most critical software and advance the cybersecurity practices the industry will need as AI grows more capable. Organizations that build or maintain critical digital infrastructure are getting early access to Claude Mythos Preview, a new class of AI model, to find and patch vulnerabilities in the systems the world depends on. Given our role in securing some of the world’s most essential infrastructure, AWS is playing an integral part in advancing this work.

Powering the project is Claude Mythos Preview, Anthropic’s most advanced AI model to date and a step-change in reasoning and AI capabilities for cybersecurity. Claude Mythos Preview represents a fundamentally new model class: more intelligent and capable than Anthropic’s previous frontier models, with higher performance on cybersecurity, software coding, and complex reasoning tasks.

As part of Project Glasswing, we’ve already applied Claude Mythos Preview to critical AWS codebases that undergo continuous AI-powered security reviews, and even in those well-tested environments, it’s helped us identify additional opportunities to strengthen our code. In our internal testing, Claude Mythos Preview has proven more productive than previous models at surfacing security findings, requiring less manual guidance from our engineers to deliver actionable results. We’ve also given early access to a select group of AWS customers, who are deploying Claude Mythos Preview in their own security workflows and helping shape how the model evolves. For us, Claude Mythos Preview is a natural extension of the AI tools we already use, and as the technology grows more powerful, so must our defenses.

This is exactly the kind of innovation that drives our work, and we’ve been working closely with Anthropic to help ensure Claude Mythos Preview is ready for enterprise use. AWS is Anthropic’s primary cloud provider for mission-critical workloads, safety research, and foundation model development. More broadly, AWS provides the foundational infrastructure that the world’s leading AI companies rely on to build, train, and deploy their most advanced models. We’re bringing decades of security experience to this partnership, helping to ensure Claude Mythos Preview is ready for even more organizations to build upon and operate securely at scale.

Claude Mythos Preview signals an upcoming wave of models that can find vulnerabilities and build working exploits at a scale and speed we haven’t seen before. Anthropic and AWS are taking a deliberately cautious approach to release. Access begins with a small number of organizations, prioritizing internet-critical companies and open-source maintainers whose software and digital services impact hundreds of millions of users. The goal: find and fix vulnerabilities in the world’s most critical software. Claude Mythos Preview is available in gated research preview through Amazon Bedrock with enterprise-grade security controls, including customer-managed encryption, VPC isolation, and detailed logging, so your team can explore Claude Mythos Preview’s capabilities without exposing production assets to unnecessary risk.

AWS architects services with security at the core

Our work with Project Glasswing is grounded in a philosophy we’ve developed over two decades of securing mission-critical workloads: you can’t wait for threats to materialize before building your defenses. You have to look around corners, adopt new technologies, build protections first, deploy them in your own operations at scale, and refine them based on what you learn.

That’s exactly what we’ve done at AWS with AI and security. Our approach spans the full spectrum: proactive defense through threat hunting and vulnerability research, dynamic response to active campaigns, and third-party certifications that verify our security practices meet the highest industry standards. This operational experience has taught us where AI accelerates security work and where human judgment remains essential. And it’s reinforced that security innovation must be pragmatic: proven in production before we ask you to rely on it.

That’s also why we help define what secure AI looks like. We became the first major cloud provider to achieve ISO 42001 certification for AI services. We’re active participants in OWASP, the Coalition for Secure AI, and the Frontier Model Safety Framework. And we co-founded the Open Cybersecurity Schema Framework (OCSF) to enable better threat intelligence sharing across the ecosystem. The AWS Nitro System provides mathematical isolation for workloads. Our zero-operator access architecture means AWS personnel can’t access your data. These aren’t aspirational goals. They’re how we operate today, at scale, every day.

Amazon Bedrock is where these principles come to life for AI. It provides policy-enforced access controls, built-in evaluation tools to measure how effectively models identify and validate vulnerabilities, and the ability to run workloads inside your own virtual private cloud. AWS is also the first cloud provider to achieve FedRAMP High and Department of Defense Security Requirements Guide Impact Level 4 and 5 authorizations for generally available Claude foundation models, reinforcing that Amazon Bedrock is where the most security-sensitive organizations already trust Anthropic’s technology.

How to get started today

The same principles that guide our work at AWS scale apply regardless of which AI tools you’re using: comprehensive observability, defense in depth, automation where it adds value, and human judgment where it’s essential. Here’s how to put them into practice.

Prepare for the next generation of AI security. Claude Mythos Preview signals an upcoming wave of AI models that will transform cybersecurity. Start strengthening your security posture now so your organization is ready as these capabilities become more broadly available. Claude Mythos Preview is available in gated preview through Amazon Bedrock, and access is limited to an initial allow-list of organizations. If your organization has been allow-listed, your AWS account team will reach out directly.

Run on-demand penetration testing with AWS Security Agent. Now generally available, AWS Security Agent delivers autonomous penetration testing that operates 24/7 at a fraction of the cost of manual penetration tests. It transforms penetration testing from a periodic bottleneck into an on-demand capability that scales with your development velocity across AWS, Azure, GCP, other cloud providers, and on-premises. AWS Security Agent represents a new class of frontier agents: autonomous systems that work independently to achieve goals, scale to tackle concurrent tasks, and run persistently without constant human oversight. It deploys specialized AI agents to discover, validate, and report security vulnerabilities through sophisticated multi-step attack scenarios. Unlike traditional scanners that generate findings without validation, AWS Security Agent identifies potential vulnerabilities, then attempts to exploit them with targeted payloads and attack chains to confirm they are legitimate security risks. Each finding includes CVSS risk scores, application-specific severity ratings, detailed reproduction steps, and remediation suggestions. The result: penetration testing that once took weeks now completes in hours, and security coverage that scales across your entire application portfolio, not just your most critical systems. New customers can explore AWS Security Agent with a 2-month free trial.

Build AI applications you can trust with Amazon Bedrock. For teams building with generative AI, the challenge isn’t just making AI work, it’s making AI work safely. Amazon Bedrock provides the security and safety controls you need to deploy AI responsibly. Its Automated Reasoning capability is the first and only AI safeguard to use formal logic to help prevent factual errors from hallucinations, providing verifiable explanations with 99% accuracy, a capability we’ve refined over more than a decade of applying formal methods across AWS storage, identity, and networking. Amazon Bedrock also provides customizable guardrails that block harmful content and enforce your content policies, along with comprehensive observability to track AI behavior and detect anomalies across your workloads.

The threat landscape isn’t waiting

The threat landscape isn’t waiting for us to catch up. Nation-state actors, ransomware operators, and supply chain attackers are already using AI to scale their operations. Our job is to stay ahead by building defenses first, deploying them at scale, and sharing what we learn so the entire community benefits.

That’s what we do every day at AWS. We prove technology works in our own operations before we ask customers to rely on it. We set standards rather than follow them. And we look around corners to address tomorrow’s challenges today.

As AI capabilities continue to evolve, this approach won’t change. We’ll keep building defenses first, refining them at scale, and working with partners like Anthropic to ensure the next generation of AI security tools meets the real-world needs of enterprises defending at this scale.

Learn More

If you have feedback about this post, submit comments in the Comments section below.

Amy Herzog

Amy Herzog is Vice President and Chief Information Security Officer (CISO) at Amazon Web Services (AWS) where she leads a global organization of cloud security professionals in a company in which security is the top priority. Prior to joining AWS, Amy served as CISO for Amazon’s Devices and Services, Media and Entertainment, and Advertising businesses, overseeing the security of consumer technology offerings such as Alexa+ and Ring, and playing a key role in the secure development of Project Kuiper, Amazon’s initiative to provide fast, reliable broadband to customers and communities around the world through low earth orbit satellites.

Unlock efficient model deployment: Simplified Inference Operator setup on Amazon SageMaker HyperPod

Post Syndicated from Shreya Gangishetty original https://aws.amazon.com/blogs/architecture/unlock-efficient-model-deployment-simplified-inference-operator-setup-on-amazon-sagemaker-hyperpod/

Amazon SageMaker HyperPod offers an end-to-end experience supporting the full lifecycle of AI development—from interactive experimentation and training to inference and post-training workflows. The SageMaker HyperPod Inference Operator is a Kubernetes controller that manages the deployment and lifecycle of models on HyperPod clusters, offering flexible deployment interfaces (kubectl, Python SDK, SageMaker Studio UI, or HyperPod CLI), advanced autoscaling with dynamic resource allocation, and comprehensive observability that tracks critical metrics like time-to-first-token, latency, and GPU utilization.

Deploying inference workloads on Kubernetes-native infrastructure has traditionally required AI teams to navigate a maze of Helm charts, IAM role configurations, dependency management, and manual upgrades — often taking hours before a single model can serve predictions. Today, we’re announcing the Amazon SageMaker HyperPod Inference Operator as a native EKS add-on, enabling one-click installation and managed upgrades directly from the SageMaker console. This eliminates the need for manual Helm charts, complex IAM configuration tweaks, and downtime during upgrades.

In this post, we walk through the new installation experience, demonstrate three deployment methods (console, CLI, and Terraform), and show how features like multi-instance-type deployment and native node affinity give you fine-grained control over inference scheduling

Simplified installation experience

The new installation experience addresses three key customer scenarios with streamlined workflows:

New HyperPod clusters: Automatic installation

When creating new HyperPod clusters through the SageMaker console’s Quick Setup or Custom Setup workflows, the Inference Operator along with necessary dependencies is now installed through EKS add-on automatically as part of the cluster creation process. This eliminates the need for post-deployment configuration and ensures your cluster is ready for model deployments immediately upon creation along with one click upgrades.

Existing clusters: One-click installation

For existing HyperPod clusters, customers can install the Inference Operator with a single click through the SageMaker console. The installation automatically:

  • Creates required IAM roles with appropriate trust relationships and permissions
  • Sets up S3 buckets for TLS certificate storage
  • Configures VPC endpoints for secure S3 access
  • Installs dependency add-ons (cert-manager, S3 CSI driver, FSx CSI driver, metrics-server)
  • Deploys the Inference Operator as an EKS add-on

Managed upgrades and lifecycle

The EKS add-on integration provides standardized version management with one-click upgrades through the AWS console or CLI. This ensures customers can easily adopt new features and security updates without complex manual procedures.

The below prerequisite resources are needed to be setup before installing the Inference operator add-on. These prerequisites will be setup if SageMaker AI console is used to setup Inference operator. However, if EKS cli or console is used, these prerequisites will need to be created manually and passed to the add-on through configuration parameters. We discuss these approaches in Installation Methods.

List of prerequisites

  1. EKS add-ons (S3 Mountpoint csi driver add-on, FsX add-on, Cert Manager add-on, Metrics server add-on)
  2. IAM roles (Inference operator execution role, ALB role, KEDA role, Optional JumpStart Gated models role)
  3. Infrastructure (S3 bucket to manage TLS certificates, OIDC association on the cluster,

For more information refer to this trouble shooting guide.

Installation methods

Method 1: Install SageMaker HyperPod Inference Add-on through SageMaker UI (Recommended)

The SageMaker console provides the most streamlined experience with two installation options:

Quick install: Automatically creates all required resources with optimized defaults, including IAM roles, S3 buckets, and dependency add-ons. This option is ideal for getting started quickly with minimal configuration decisions.

Custom install: Provides flexibility to specify existing resources or customize configurations while maintaining the one-click experience. Customers can choose to reuse existing IAM roles, S3 buckets, or dependency add-ons based on their organizational requirements.

Amazon SageMaker HyperPod Inference Operator installation page showing Quick install and Custom install options with component details including AWS Load Balancer Controller, KEDA, and CSI drivers

Prerequisites

  • An existing Amazon SageMaker HyperPod cluster with EKS orchestration
  • IAM permissions for EKS cluster administration
  • kubectl configured for cluster access

Installation steps

  1. Navigate to the SageMaker Console: Go to HyperPod Clusters → Cluster Management
  2. Select Your Cluster: Choose the cluster where you want to install the Inference Operator

HyperPod Dashboard main page

  1. Choose Installation Type: Navigate to Inference tab. Select Quick Install for automated setup or Custom Install for configuration flexibility

SageMaker HyperPod Inference tab interface showing disabled cluster role and installation options for managing inference workloads

  1. Configure Options: If choosing Custom Install, specify existing resources or customize settings as needed
  2. Install: Choose Install to begin the automated installation process
  3. Verify: Check the installation status through the console, or by running kubectl get pods -n hyperpod-inference-system, or by checking the add-on status with aws eks describe-addon --cluster-name CLUSTER-NAME --addon-name amazon-sagemaker-hyperpod-inference --region REGION

After the add-on is successfully installed, you can deploy models using the Model deployments document or navigate to Deploying Your First Model section below.

Method 2: Install SageMaker HyperPod Inference add-on through EKS APIs

For customers preferring command-line workflows, the Inference Operator can be installed directly using the EKS CLI. Note that all prerequisite resources (IAM roles, S3 buckets, VPC endpoints) and dependency add-ons must be created manually before installing the Inference Operator add-on. For detailed setup instructions, see the installation guide.

aws eks create-addon \
  --cluster-name my-hyperpod-cluster \
  --addon-name amazon-sagemaker-hyperpod-inference \
  --addon-version v1.0.0-eksbuild.1 \
  --configuration-values '{
    "executionRoleArn": "arn:aws:iam::ACCOUNT-ID:role/SageMakerHyperPodInference-inference-role",
    "tlsCertificateS3Bucket": "hyperpod-tls-certificate-bucket",
    "hyperpodClusterArn": "arn:aws:sagemaker:REGION:ACCOUNT-ID:cluster/CLUSTER-ID",
    "alb": {
      "serviceAccount": {
        "create": true,
        "roleArn": "arn:aws:iam::ACCOUNT-ID:role/alb-controller-role"
      }
    },
    "keda": {
      "auth": {
        "aws": {
          "irsa": {
            "roleArn": "arn:aws:iam::ACCOUNT-ID:role/keda-operator-role"
          }
        }
      }
    }
  }' \
  --region us-west-2

Method 3: Install SageMaker HyperPod Inference add-on through Terraform deployment

Organizations utilizing Terraform for Infrastructure as Code (IaC) can deploy HyperPod clusters using the provided modules in the awesome-distributed-training GitHub repository.

To enable the HyperPod inference operator, set the create_hyperpod_inference_operator_module variable to true within your custom.tfvars file, as shown below:

kubernetes_version    = "1.33"
eks_cluster_name      = "tf-eks-cluster"
hyperpod_cluster_name = "tf-hp-cluster"
resource_name_prefix  = "tf-eks-test"
aws_region            = "us-east-1"

instance_groups = [
    {
        name                      = "accelerated-instance-group-1"
        instance_type             = "ml.g5.8xlarge",
        instance_count            = 2,
        availability_zone_id      = "use1-az2",
        ebs_volume_size_in_gb     = 100,
        threads_per_core          = 1,
        enable_stress_check       = false,
        enable_connectivity_check = false,
        lifecycle_script          = "on_create.sh"
    }
]

create_hyperpod_inference_operator_module = true

In addition to the HyperPod inference operator add-on, the Terraform modules also support the task governance, training operator, and observability add-ons as well. Check out the documentation for enabling optional add-ons for more details.

Dependency management

The HyperPod inference operator includes several additional dependencies, which are enabled by default but can be toggled off if they already exist on your EKS cluster:

Dependency Module/Variable Toggle to Disable
cert-manager Installed via the HyperPod module enable_cert_manager = false
Amazon FSx for Lustre CSI Installed via FSx module create_fsx_module = false
Mountpoint for Amazon S3 CSI Bundled with Inference Operator Module enable_s3_csi_driver = false
AWS Load Balancer Controller Bundled with Inference Operator EKS add-on enable_alb_controller = false
KEDA Operator Bundled with Inference Operator EKS add-on enable_keda = false

Key benefits

Faster time to value

Teams can now deploy their first inference endpoint within minutes of cluster creation, compared to the previous multi-hour setup process. This acceleration enables faster experimentation and reduces the barrier to adoption for new teams.

Reduced complexity

The new installation experience eliminates the need to manually create and configure multiple AWS resources. Previously, customers needed to create IAM roles, policies, S3 buckets, VPC endpoints, and install multiple Kubernetes operators. Now, a single action handles all these requirements automatically.

Consistent configuration

Automated resource creation ensures consistent, secure configurations across environments. The installation process follows AWS best practices for IAM permissions, network security, and resource naming conventions.

Simplified upgrades

EKS Add-on integration provides standardized upgrade paths with rollback capabilities. Customers can confidently adopt new features and security updates through the familiar AWS console or CLI interfaces.

Advanced features integration

The simplified installation experience seamlessly integrates with advanced HyperPod inference capabilities:

Managed tiered KV cache

During installation, customers can optionally enable managed tiered KV cache with intelligent memory allocation based on instance types. This feature can reduce inference latency by up to 40% for long-context workloads while optimizing memory utilization across the cluster.

Intelligent routing

The installation automatically configures intelligent routing capabilities with multiple strategies (prefix-aware, KV-aware, round-robin) to maximize cache efficiency and minimize inference latency based on workload characteristics.

Observability integration

Built-in integration with HyperPod Observability provides immediate visibility into inference metrics, cache performance, and routing efficiency through Amazon Managed Grafana dashboards.

Deploying your first model

Once the add-on is installed, you can deploy models using the InferenceEndpointConfig or JumpStart models custom resources. Here’s an example configuration for deploying a Llama model:

apiVersion: inference.sagemaker.aws.amazon.com/v1
kind: JumpStartModel
metadata:
  name: deepseek-test-endpoint
spec:
  model:
    modelId: "deepseek-llm-r1-distill-qwen-1-5b"
  sageMakerEndpoint:
    name: deepseek-test-endpoint
  server:
    instanceType: "ml.g5.8xlarge"

New features

Multi-Instance Type Deployment HyperPod Inference supports multi-instance type deployment, enhancing deployment reliability and resource utilization. You can specify a prioritized list of instance types in your deployment configuration, and the system automatically selects from available alternatives when your preferred instance type lacks capacity. The Kubernetes scheduler evaluates instance types in priority order using node affinity rules based scheduling, seamlessly placing workloads on the highest-priority available instance type. In the example below, when deploying a model from S3, ml.p4d.24xlarge has the highest priority and will be selected first if memory capacity is available. If ml.p4d.24xlarge is unavailable, the scheduler automatically falls back to ml.g5.24xlarge, and finally to ml.g5.8xlarge as the last resort.

apiVersion: inference.sagemaker.aws.amazon.com/v1
kind: InferenceEndpointConfig
metadata:
  name: lmcache-test-1
  namespace: default
spec:
  replicas: 13
  modelName: Llama-3.1-8B-Instruct
  instanceTypes: ["ml.p4d.24xlarge","ml.g5.24xlarge","ml.g5.8xlarge"]

This is implemented using Kubernetes node affinity rules with requiredDuringSchedulingIgnoredDuringExecution to restrict scheduling to the specified instance types, and preferredDuringSchedulingIgnoredDuringExecution with descending weights to enforce priority ordering.

Node affinity
For scenarios requiring more granular scheduling control — such as excluding spot instances, preferring specific availability zones, or targeting nodes with custom labels — HyperPod Inference exposes Kubernetes’ native nodeAffinity directly in the InferenceEndpointConfig spec. This gives you the full expressiveness of Kubernetes scheduling primitives.

apiVersion: inference.sagemaker.aws.amazon.com/v1
kind: InferenceEndpointConfig
metadata:
  name: lmcache-test-1
  namespace: default
spec:
  replicas: 15
  modelName: Llama-3.1-8B-Instruct
  nodeAffinity:
    preferredDuringSchedulingIgnoredDuringExecution:
    - weight: 100
      preference:
        matchExpressions:
        - key: node.kubernetes.io/instanceType
          operator: In
          values: ["ml.g5.4xlarge"]
  worker:
    resources:
      limits:
        nvidia.com/gpu: "1"
      requests:
        cpu: "6"
        memory: 30Gi
        nvidia.com/gpu: "1"

Clean up

To clean up your environment after completing this walkthrough, follow these steps to remove the deployed models and uninstall the Inference Operator add-on from your HyperPod cluster.

Removing Inference Operator add-on

Through the SageMaker console:

  1. Navigate to SageMaker Console → HyperPod Clusters → Cluster Management
  2. Select your cluster and go to the Inference tab
  3. Choose Remove to uninstall the Inference Operator add-on and associated resources

Alternatively, using the AWS CLI:

aws eks delete-addon \
--cluster-name <my-hyperpod-cluster> \
--addon-name amazon-sagemaker-hyperpod-inference \
--region <region>

Delete the deployed models

# Delete JumpStartModel deployment
kubectl delete jumpstartmodel <model-name> -n <namespace>

# Or for InferenceEndpointConfig deployment
kubectl delete inferenceendpointconfig <endpoint-name> -n <namespace>

Migration path for existing users

Automated migration script is hosted in public GitHub that transitions the HyperPod Inference Operator from Helm to EKS add-on with built-in rollback capabilities if add-on installation fails. Backup files are stored in /tmp/hyperpod-migration-backup-<timestamp>/ for manual rollback if needed.

Key features

  • Auto-Discovery: Derives configuration from existing Helm deployment (roles, buckets, dependencies)
  • Safe Migration: Scales down Helm deployments before add-on installation, validates prerequisites
  • Dependency Handling: Migrates S3/FSx CSI drivers, cert-manager, and metrics-server to add-ons
  • Rollback Support: Preserves original resources and restores on failure

IAM Roles created

  1. Execution Role (Inference Operator + S3 TLS access)
  2. JumpStart Gated Model Role
  3. ALB Controller Role
  4. KEDA Operator Role

Examples for running the script

# to follow step by step guide
./helm_to_addon.sh --cluster-name <my-cluster> --region us-east-1 

# no prompts needed except for initiating rollback in case of failure
./helm_to_addon.sh --cluster-name <my-cluster> --region us-east-1 --auto-approve 

# To skip the dependencies FSX, S3, Metricsserver, cert manager migration from Inference operator helm to respective add-ons
./helm_to_addon.sh --cluster-name my-cluster —region us-east-1 --skip-dependencies-migration

Migration flow

  1. Validate existing Helm installation
  2. Auto-derive configuration and create new IAM roles
  3. Tag resources (ALBs, ACM certs, S3 objects) with CreatedBy: HyperPodInference
  4. Install dependency add-ons (S3, FSx, cert-manager) if dependent CRDs don’t exist
  5. Scale down Helm deployments for ALB, KEDA and Inference operator
  6. Install Inference Operator add-on with OVERWRITE flag
  7. Clean up old Helm resources
  8. Migrate Helm-installed dependencies that are installed through Inference operator main chart to add-ons. To skip this step provide --skip-dependencies flag.

Benefits

  • Simplified management through EKS console/APIs
  • Automated updates via EKS add-on mechanisms
  • Native EKS integration
  • Zero downtime migration with rollback safety

Conclusion

The streamlined Inference Operator installation experience for Amazon SageMaker HyperPod eliminates infrastructure complexity and accelerates time to value for machine learning teams. With one-click installation, automated resource management, and seamless upgrade capabilities, teams can focus on deploying and optimizing their inference workloads rather than managing underlying infrastructure.

The EKS Add-on integration provides enterprise-grade lifecycle management while maintaining the flexibility to customize configurations for specific organizational requirements. Combined with advanced features like managed tiered KV cache and intelligent routing, this simplified installation experience makes high-performance inference deployment accessible to teams of all sizes.

Get started today by creating a new HyperPod cluster with the Inference Operator pre-installed, or add it to your existing clusters with a single click through the SageMaker console. For detailed add-on installation instructions and configuration options see this guide and for troubleshooting see this guide.

Appendix


About the authors

AWS Weekly Roundup: AWS DevOps Agent & Security Agent GA, Product Lifecycle updates, and more (April 6, 2026)

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-aws-devops-agent-security-agent-ga-product-lifecycle-updates-and-more-april-6-2026/

Last week, I visited AWS Hong Kong User Group with my team. Hong Kong has a small but strong community, and their energy and passion are high. They recently started a new AI user group, and we hope more people will join. I was able to strengthen my bond with the community through great food and conversation.

This week, I”ll first take a closer look at some of the key launches.

AWS DevOps Agent and Security Agent GA
At the last re:Invent, we introduced the concept of frontier agents that work autonomously across multiple steps to achieve outcomes, operating continuously until the job is done. The first two—AWS DevOps Agent and AWS Security Agent—are now generally available after the preview.

AWS DevOps Agent helps you run cloud operations—investigating incidents, reducing time to resolution, and preventing issues before they happen. Customers like United Airlines, Western Governors University, and T-Mobile are already using DevOps Agent to accelerate incident response and simplify operations at scale. At WGU, resolution time dropped from hours to minutes, and in preview customers report up to 75% lower MTTR and 3 to 5 times faster resolution. Learn more in Sébastien’s preview blog post and GA announcement.

AWS Security Agent brings continuous, context-aware penetration testing into the development lifecycle. This agent operates like a human penetration tester. Customers including LG CNS, HENNGE, and Wayspring are seeing strong results. At LG CNS, teams estimate over 50% faster testing and ~30% lower costs, along with significantly fewer false positives. Learn more in Esra’s preview blog post and GA announcement.

Both are designed to work across AWS cloud, multicloud, and on-prem environments. You can have an always-available teammate that can handle the heavy lifting, so you can focus on what matters most.

AWS Service Availability Updates
When the availability of an AWS service or feature changes, we provide customers guidance in AWS Product Lifecycle Changes on available alternatives and support for migration so that disruptions to your operations are minimized. The following lifecycle changes were updated on March 31, 2026.

We understand that changes in availability can impact your operations. For specific guidance, consult the relevant service documentation or contact AWS Support.

Last week’s launches
Here are last week’s launches that caught my attention:

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Additional updates
Here are some additional news items that you might find interesting:

For a full list of AWS blog posts, be sure to keep an eye on the AWS Blogs page.

Learn more about AWS, browse and join upcoming AWS led in-person and virtual events, startup events, and developer-focused events as well as AWS Summits and AWS Community Days. Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Channy