Tag Archives: Customer Solutions

How the BMW Group analyses semiconductor demand with AWS Glue

Post Syndicated from Göksel SARIKAYA original https://aws.amazon.com/blogs/big-data/how-the-bmw-group-analyses-semiconductor-demand-with-aws-glue/

This is a guest post co-written by Maik Leuthold and Nick Harmening from BMW Group.

The BMW Group is headquartered in Munich, Germany, where the company oversees 149,000 employees and manufactures cars and motorcycles in over 30 production sites across 15 countries. This multinational production strategy follows an even more international and extensive supplier network.

Like many automobile companies across the world, the BMW Group has been facing challenges in its supply chain due to the worldwide semiconductor shortage. Creating transparency about BMW Group’s current and future demand of semiconductors is one key strategic aspect to resolve shortages together with suppliers and semiconductor manufacturers. The manufacturers need to know BMW Group’s exact current and future semiconductor volume information, which will effectively help steer the available worldwide supply.

The main requirement is to have an automated, transparent, and long-term semiconductor demand forecast. Additionally, this forecasting system needs to provide data enrichment steps including byproducts, serve as the master data around the semiconductor management, and enable further use cases at the BMW Group.

To enable this use case, we used the BMW Group’s cloud-native data platform called the Cloud Data Hub. In 2019, the BMW Group decided to re-architect and move its on-premises data lake to the AWS Cloud to enable data-driven innovation while scaling with the dynamic needs of the organization. The Cloud Data Hub processes and combines anonymized data from vehicle sensors and other sources across the enterprise to make it easily accessible for internal teams creating customer-facing and internal applications. To learn more about the Cloud Data Hub, refer to BMW Group Uses AWS-Based Data Lake to Unlock the Power of Data.

In this post, we share how the BMW Group analyzes semiconductor demand using AWS Glue.

Logic and systems behind the demand forecast

The first step towards the demand forecast is the identification of semiconductor-relevant components of a vehicle type. Each component is described by a unique part number, which serves as a key in all systems to identify this component. A component can be a headlight or a steering wheel, for example.

For historic reasons, the required data for this aggregation step is siloed and represented differently in diverse systems. Because each source system and data type have its own schema and format, it’s particularly difficult to perform analytics based on this data. Some source systems are already available in the Cloud Data Hub (for example, part master data), therefore it’s straightforward to consume from our AWS account. To access the remaining data sources, we need to build specific ingest jobs that read data from the respective system.

The following diagram illustrates the approach.
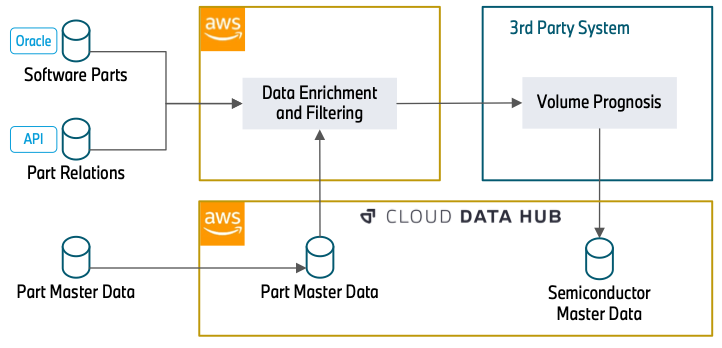
The data enrichment starts with an Oracle Database (Software Parts) that contains part numbers that are related to software. This can be the control unit of a headlight or a camera system for automated driving. Because semiconductors are the basis for running software, this database builds the foundation of our data processing.

In the next step, we use REST APIs (Part Relations) to enrich the data with further attributes. This includes how parts are related (for example, a specific control unit that will be installed into a headlight) and over which timespan a part number will be built into a vehicle. The knowledge about the part relations is essential to understand how a specific semiconductor, in this case the control unit, is relevant for a more general part, the headlight. The temporal information about the use of part numbers allows us to filter out outdated part numbers, which will not be used in the future and therefore have no relevance in the forecast.

The data (Part Master Data) can directly be consumed from the Cloud Data Hub. This database includes attributes about the status and material types of a part number. This information is required to filter out part numbers that we gathered in the previous steps but have no relevance for semiconductors. With the information that was gathered from the APIs, this data is also queried to extract further part numbers that weren’t ingested in the previous steps.

After data enrichment and filtering, a third-party system reads the filtered part data and enriches the semiconductor information. Subsequently, it adds the volume information of the components. Finally, it provides the overall semiconductor demand forecast centrally to the Cloud Data Hub.

Applied services

Our solution uses the serverless services AWS Glue and Amazon Simple Storage Service (Amazon S3) to run ETL (extract, transform, and load) workflows without managing an infrastructure. It also reduces the costs by paying only for the time jobs are running. The serverless approach fits our workflow’s schedule very well because we run the workload only once a week.

Because we’re using diverse data source systems as well as complex processing and aggregation, it’s important to decouple ETL jobs. This allows us to process each data source independently. We also split the data transformation into several modules (Data Aggregation, Data Filtering, and Data Preparation) to make the system more transparent and easier to maintain. This approach also helps in case of extending or modifying existing jobs.

Although each module is specific to a data source or a particular data transformation, we utilize reusable blocks inside of every job. This allows us to unify each type of operation and simplifies the procedure of adding new data sources and transformation steps in the future.

In our setup, we follow the security best practice of the least privilege principle, to ensure the information is protected from accidental or unnecessary access. Therefore, each module has AWS Identity and Access Management (IAM) roles with only the necessary permissions, namely access to only data sources and buckets the job deals with. For more information regarding security best practices, refer to Security best practices in IAM.

Solution overview

The following diagram shows the overall workflow where several AWS Glue jobs are interacting with each other sequentially.

As we mentioned earlier, we used the Cloud Data Hub, Oracle DB, and other data sources that we communicate with via the REST API. The first step of the solution is the Data Source Ingest module, which ingests the data from different data sources. For that purpose, AWS Glue jobs read information from different data sources and writes into the S3 source buckets. Ingested data is stored in the encrypted buckets, and keys are managed by AWS Key Management Service (AWS KMS).

After the Data Source Ingest step, intermediate jobs aggregate and enrich the tables with other data sources like components version and categories, model manufacture dates, and so on. Then they write them into the intermediate buckets in the Data Aggregation module, creating comprehensive and abundant data representation. Additionally, according to the business logic workflow, the Data Filtering and Data Preparation modules create the final master data table with only actual and production-relevant information.

The AWS Glue workflow manages all these ingestion jobs and filtering jobs end to end. An AWS Glue workflow schedule is configured weekly to run the workflow on Wednesdays. While the workflow is running, each job writes execution logs (info or error) into Amazon Simple Notification Service (Amazon SNS) and Amazon CloudWatch for monitoring purposes. Amazon SNS forwards the execution results to the monitoring tools, such as Mail, Teams, or Slack channels. In case of any error in the jobs, Amazon SNS also alerts the listeners about the job execution result to take action.

As the last step of the solution, the third-party system reads the master table from the prepared data bucket via Amazon Athena. After further data engineering steps like semiconductor information enrichment and volume information integration, the final master data asset is written into the Cloud Data Hub. With the data now provided in the Cloud Data Hub, other use cases can use this semiconductor master data without building several interfaces to different source systems.

Business outcome

The project results provide the BMW Group a substantial transparency about their semiconductor demand for their entire vehicle portfolio in the present and in the future. The creation of a database with that magnitude enables the BMW Group to establish even further use cases to the benefit of more supply chain transparency and clearer and deeper exchange with first-tier suppliers and semiconductor manufacturers. It helps not only to resolve the current demanding market situation, but also to be more resilient in the future. Therefore, it’s one major step to a digital, transparent supply chain.

Conclusion

This post describes how to analyze semiconductor demand from many data sources with big data jobs in an AWS Glue workflow. A serverless architecture with minimal diversity of services makes the code base and architecture simple to understand and maintain. To learn more about how to use AWS Glue workflows and jobs for serverless orchestration, visit the AWS Glue service page.


About the authors

Maik Leuthold is a Project Lead at the BMW Group for advanced analytics in the business field of supply chain and procurement, and leads the digitalization strategy for the semiconductor management.

Nick Harmening is an IT Project Lead at the BMW Group and an AWS certified Solutions Architect. He builds and operates cloud-native applications with a focus on data engineering and machine learning.
Göksel Sarikaya is a Senior Cloud Application Architect at AWS Professional Services. He enables customers to design scalable, cost-effective, and competitive applications through the innovative production of the AWS platform. He helps them to accelerate customer and partner business outcomes during their digital transformation journey.
Alexander Tselikov is a Data Architect at AWS Professional Services who is passionate about helping customers to build scalable data, analytics and ML solutions to enable timely insights and make critical business decisions.
Rahul Shaurya is a Senior Big Data Architect at Amazon Web Services. He helps and works closely with customers building data platforms and analytical applications on AWS. Outside of work, Rahul loves taking long walks with his dog Barney.
How Huron built an Amazon QuickSight Asset Catalogue with AWS CDK Based Deployment Pipeline

Post Syndicated from Corey Johnson original https://aws.amazon.com/blogs/big-data/how-huron-built-an-amazon-quicksight-asset-catalogue-with-aws-cdk-based-deployment-pipeline/

This is a guest blog post co-written with Corey Johnson from Huron.

Having an accurate and up-to-date inventory of all technical assets helps an organization ensure it can keep track of all its resources with metadata information such as their assigned oners, last updated date, used by whom, how frequently and more. It helps engineers, analysts and businesses access the most up-to-date release of the software asset that bring accuracy to the decision-making process. By keeping track of this information, organizations will be able to identify technology gaps, refresh cycles, and expire assets as needed for archival.

In addition, an inventory of all assets is one of the foundational elements of an organization that facilitates the security and compliance team to audit the assets for improving privacy, security posture and mitigate risk to ensure the business operations run smoothly. Organizations may have different ways of maintaining an asset inventory, that may be an Excel spreadsheet or a database with a fully automated system to keep it up-to-date, but with a common objective of keeping it accurate. Even if organizations can follow manual approaches to update the inventory records but it is recommended to build automation, so that it is accurate at any point of time.

The DevOps practices which revolutionized software engineering in the last decade have yet to come to the world of Business Intelligence solutions. Business intelligence tools by their nature use a paradigm of UI driven development with code-first practices being secondary or nonexistent. As the need for applications that can leverage the organizations internal and client data increases, the same DevOps practices (BIOps) can drive and delivery quality insights more reliably

In this post, we walk you through a solution that Huron and manage lifecycle for all Amazon QuickSight resources across the organization by collaborating with AWS Data Lab Resident Architect & AWS Professional Services team.

About Huron

Huron is a global professional services firm that collaborates with clients to put possible into practice by creating sound strategies, optimizing operations, accelerating digital transformation, and empowering businesses and their people to own their future. By embracing diverse perspectives, encouraging new ideas, and challenging the status quo, Huron creates sustainable results for the organizations we serve. To help address its clients’ growing cloud needs, Huron is an AWS Partner.

Use Case Overview

Huron’s Business Intelligence use case represents visualizations as a service, where Huron has core set of visualizations and dashboards available as products for its customers. The products exist in different industry verticals (healthcare, education, commercial) with independent development teams. Huron’s consultants leverage the products to provide insights as part of consulting engagements. The insights from the product help Huron’s consultants accelerate their customer’s transformation. As part of its overall suite of offerings, there are product dashboards that are featured in a software application following a standardized development lifecycle. In addition, these product dashboards may be forked for customer-specific customization to support a consulting engagement while still consuming from Huron’s productized data assets and datasets. In the next stage of the cycle, Huron’s consultants experiment with new data sources and insights that in turn fed back into the product dashboards.

When changes are made to a product analysis, challenges arise when a base reference analysis gets updated because of new feature releases or bug fixes, and all the customer visualizations that are created from it also need to be updated. To maintain the integrity of embedded visualizations, all metadata and lineage must be available to the parent application. This access to the metadata supports the need for updating visuals based on changes as well as automating row and column level security ensuring customer data is properly governed.

In addition, few customers request customizations on top of the base visualizations, for which Huron team needs to create a replica of the base reference and then customize it for the customer. These are maintained by Huron’s in the field consultants rather than the product development team. These customer specific visualizations create operational overhead because they require Huron to keep track of new customer specific visualizations and maintain them for future releases when the product visuals change.

Huron leverages Amazon QuickSight for their Business Intelligence (BI) reporting needs, enabling them to embed visualizations at scale with higher efficiency and lower cost. A large attraction for Huron to adopt QuickSight came from the forward-looking API capabilities that enable and set the foundation for a BIOps culture and technical infrastructure. To address the above requirement, Huron Global Product team decided to build a QuickSight Asset Tracker and QuickSight Asset Deployment Pipeline.

The QuickSight Asset tracker serves as a catalogue of all QuickSight resources (datasets, analysis, templates, dashboards etc.) with its interdependent relationship. It will help;

  • Create an inventory of all QuickSight resources across all business units
  • Enable dynamic embedding of visualizations and dashboards based on logged in user
  • Enable dynamic row and column level security on the dashboards and visualizations based on the logged-in user
  • Meet compliance and audit requirements of the organization
  • Maintain the current state of all customer specific QuickSight resources

The solution integrates an AWS CDK based pipeline to deploy QuickSight Assets that:

  • Supports Infrastructure-as-a-code for QuickSight Asset Deployment and enables rollbacks if required.
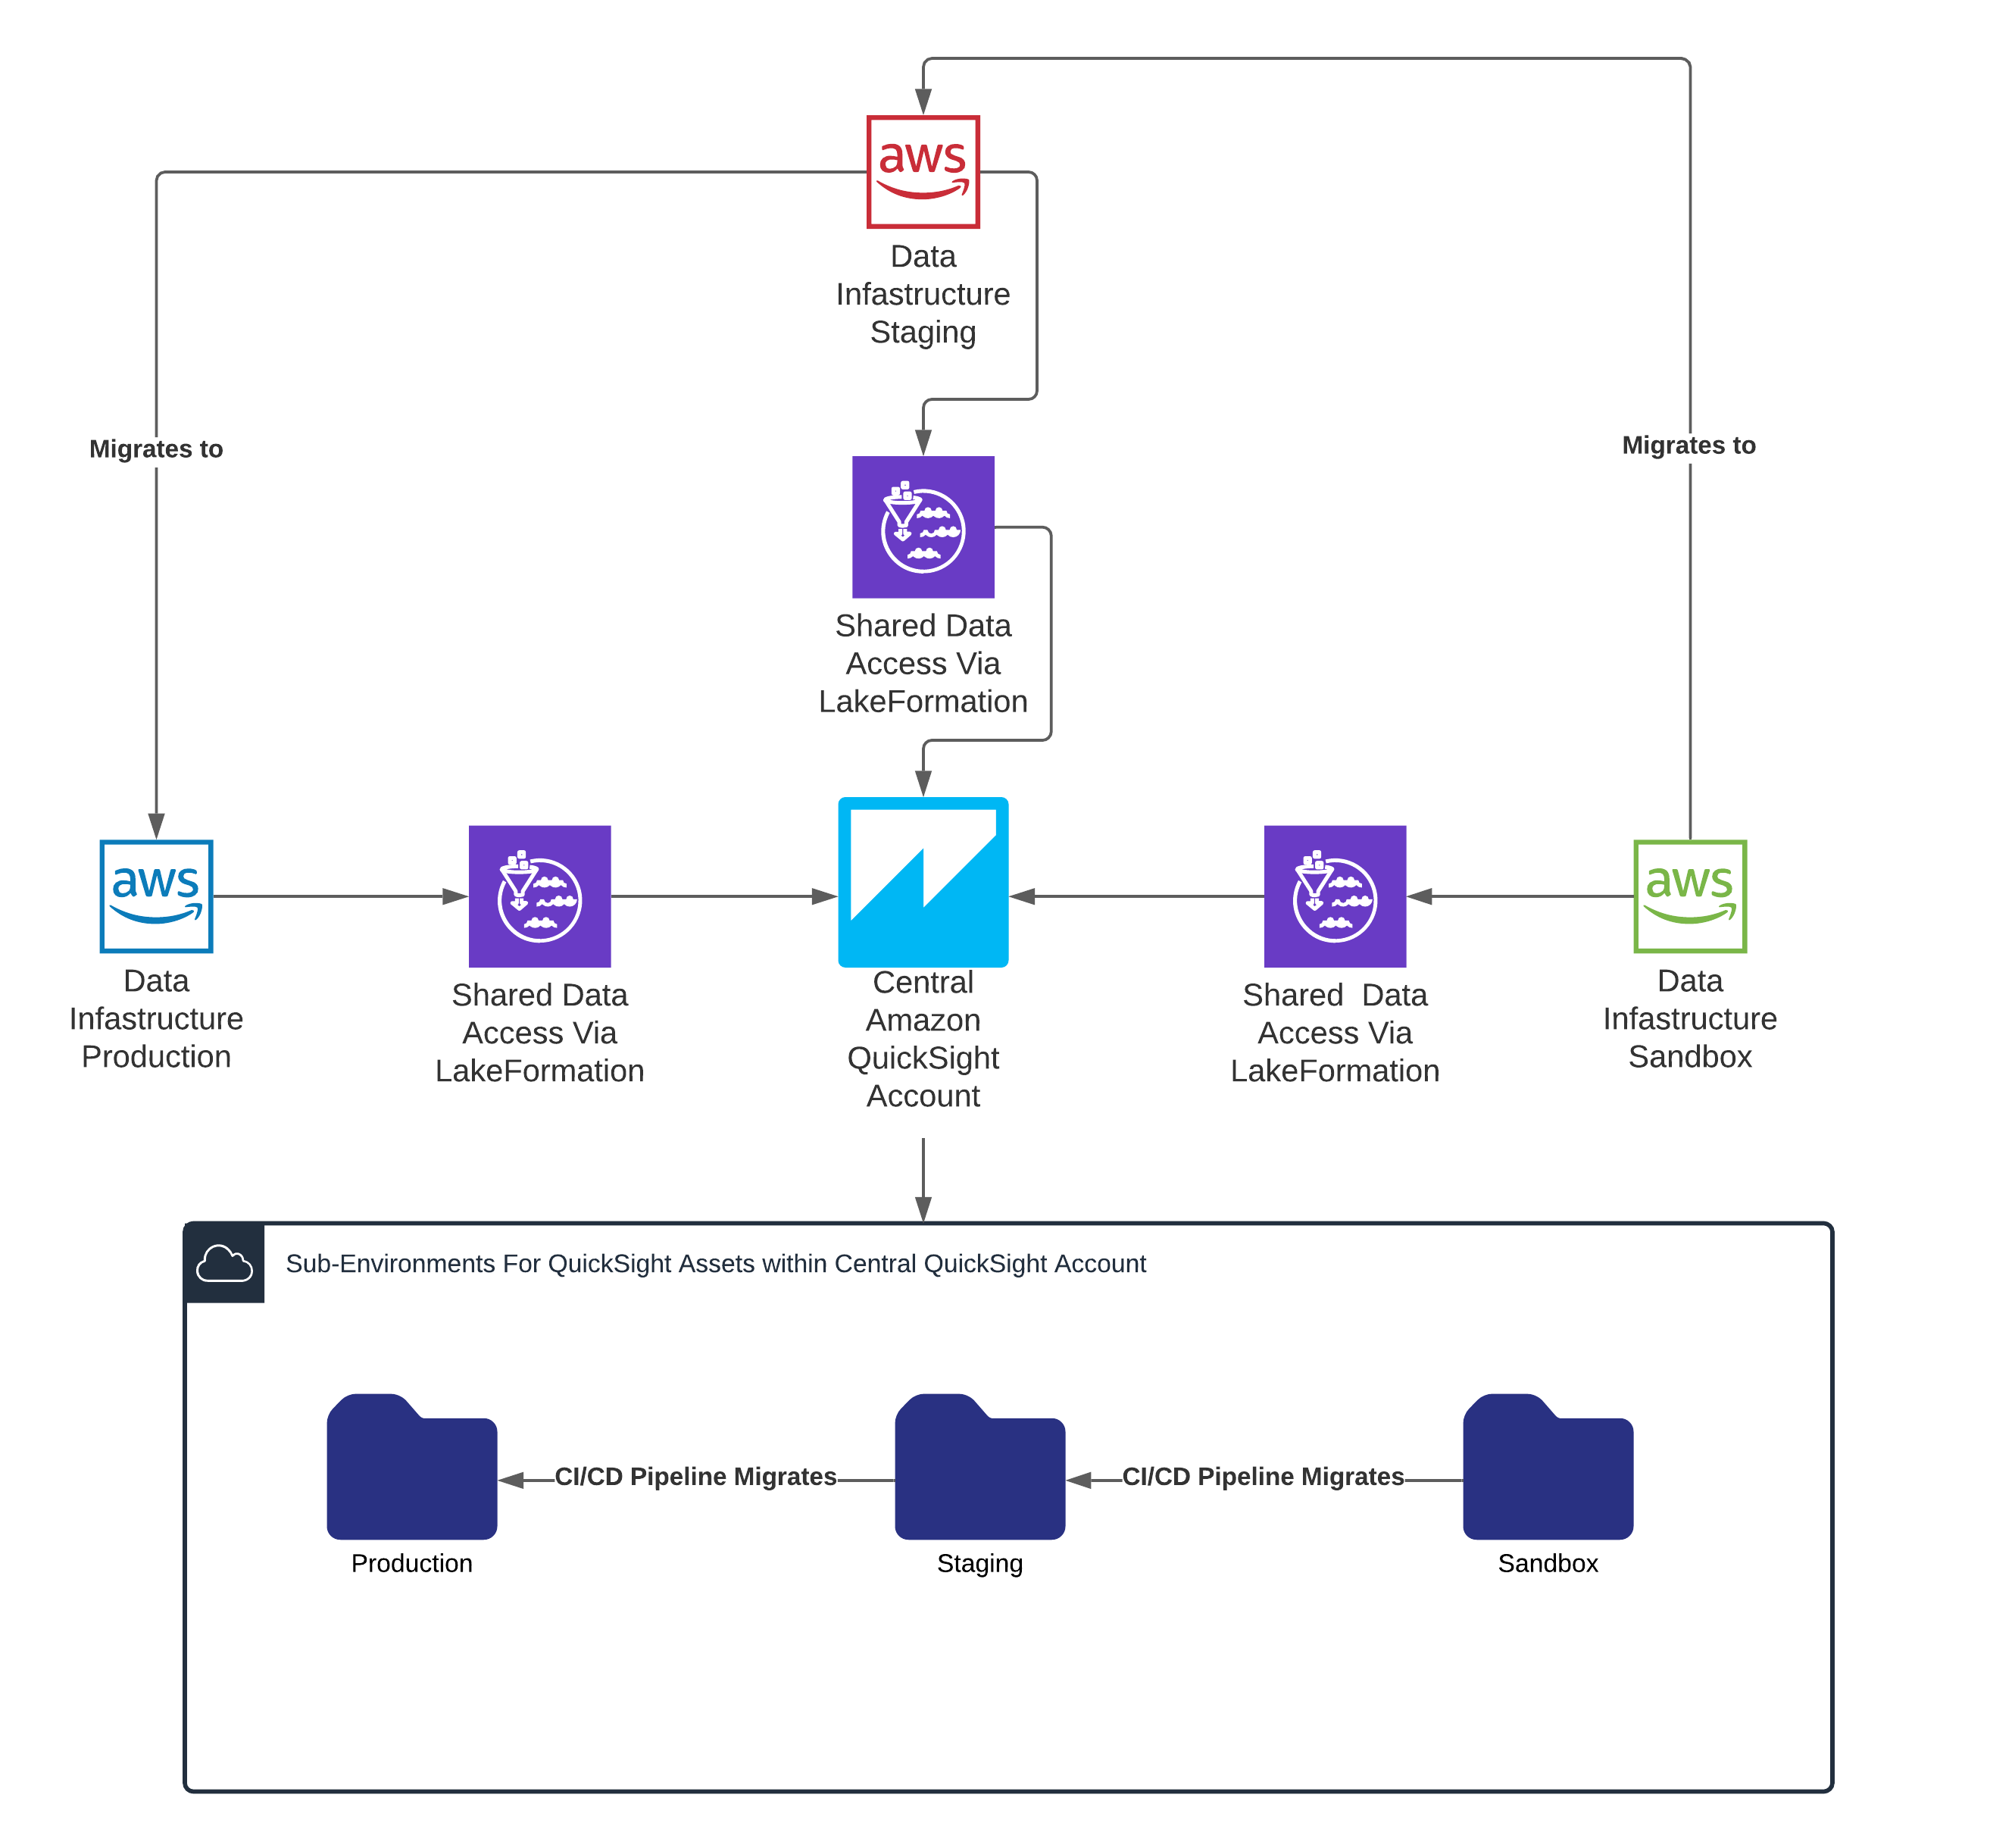
  • Enables separation of development, staging and production environments using QuickSight folders that reduces the burden of multi-account management of QuickSight resources.
  • Enables a hub-and-spoke model for Data Access in multiple AWS accounts in a data mesh fashion.

QuickSight Asset Tracker and QuickSight Asset Management Pipeline – Architecture Overview

The QuickSight Asset Tracker was built as an independent service, which was deployed in a shared AWS service account that integrated Amazon Aurora Serverless PostgreSQL to store metadata information, AWS Lambda as the serverless compute and Amazon API Gateway to provide the REST API layer.

It also integrated AWS CDK and AWS CloudFormation to deploy the product and customer specific QuickSight resources and keep them in consistent and stable state. The metadata of QuickSight resources, created using either AWS console or the AWS CDK based deployment were maintained in Amazon Aurora database through the QuickSight Asset Tracker REST API service.

The CDK based deployment pipeline is triggered via a CI/CD pipeline which performs the following functions:

  1. Takes the ARN of the QuickSight assets (dataset, analysis, etc.)
  2. Describes the asset and dependent resources (if selected)
  3. Creates a copy of the resource in another environment (in this case a QuickSight folder) using CDK

The solution architecture integrated the following AWS services.

  • Amazon Aurora Serverless integrated as the backend database to store metadata information of all QuickSight resources with customer and product information they are related to.
  • Amazon QuickSight as the BI service using which visualization and dashboards can be created and embedded into the online applications.
  • AWS Lambda as the serverless compute service that gets invoked by online applications using Amazon API Gateway service.
  • Amazon SQS to store customer request messages, so that the AWS CDK based pipeline can read from it for processing.
  • AWS CodeCommit is integrated to store the AWS CDK deployment scripts and AWS CodeBuild, AWS CloudFormation integrated to deploy the AWS resources using an infrastructure as a code approach.
  • AWS CloudTrail is integrated to audit user actions and trigger Amazon EventBridge rules when a QuickSight resource is created, updated or deleted, so that the QuickSight Asset Tracker is up-to-date.
  • Amazon S3 integrated to store metadata information, which is used by AWS CDK based pipeline to deploy the QuickSight resources.
  • AWS LakeFormation enables cross-account data access in support of the QuickSight Data Mesh

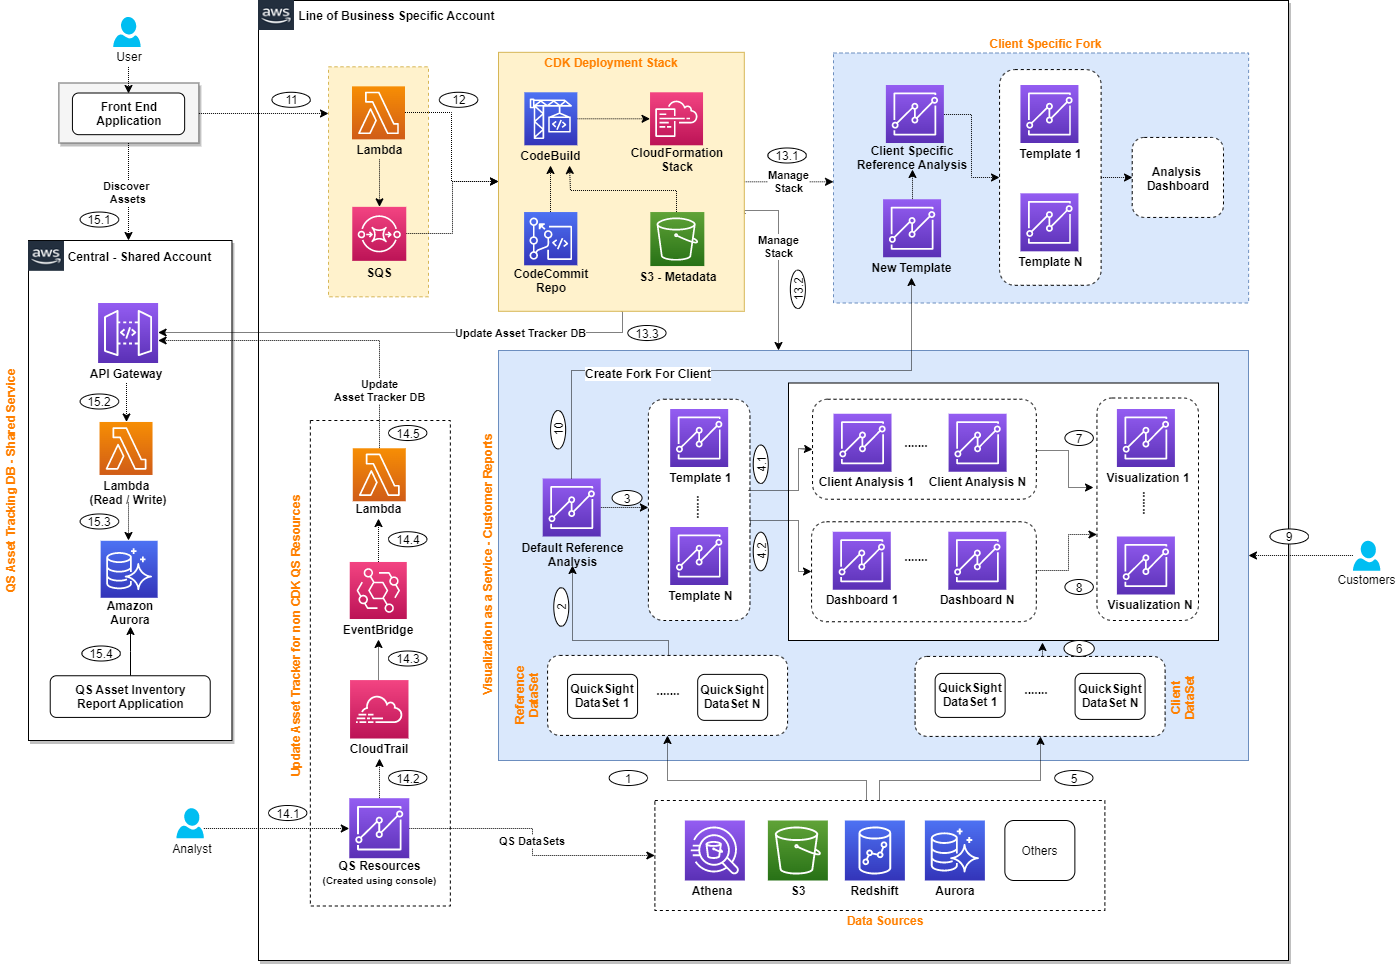
The following provides a high-level view of the solution architecture.

Architecture Walkthrough:

The following provides a detailed walkthrough of the above architecture.

  • QuickSight Dataset, Template, Analysis, Dashboard and visualization relationships:
    • Steps 1 to 2 represent QuickSight reference analysis reading data from different data sources that may include Amazon S3, Amazon Athena, Amazon Redshift, Amazon Aurora or any other JDBC based sources.
    • Step 3 represents QuickSight templates being created from reference analysis when a customer specific visualization needs to be created and step 4.1 to 4.2 represents customer analysis and dashboards being created from the templates.
    • Steps 7 to 8 represent QuickSight visualizations getting generated from analysis/dashboard and step 6 represents the customer analysis/dashboard/visualizations referring their own customer datasets.
    • Step 10 represents a new fork being created from the base reference analysis for a specific customer, which will create a new QuickSight template and reference analysis for that customer.
    • Step 9 represents end users accessing QuickSight visualizations.
  • Asset Tracker REST API service:
    • Step 15.2 to 15.4 represents the Asset Tracker service, which is deployed in a shared AWS service account, where Amazon API Gateway provides the REST API layer, which invokes AWS Lambda function to read from or write to backend Aurora database (Aurora Serverless v2 – PostgreSQL engine). The database captures all relationship metadata between QuickSight resources, its owners, assigned customers and products.
  • Online application – QuickSight asset discovery and creation
    • Step 15.1 represents the front-end online application reading QuickSight metadata information from the Asset Tracker service to help customers or end users discover visualizations available and be able to dynamically render based on the user login.
    • Step 11 to 12 represents the online application requesting creation of new QuickSight resources, which pushes requests to Amazon SQS and then AWS Lambda triggers AWS CodeBuild to deploy new QuickSight resources. Step 13.1 and 13.2 represents the CDK based pipeline maintaining the QuickSight resources to keep them in a consistent state. Finally, the AWS CDK stack invokes the Asset Tracker service to update its metadata as represented in step 13.3.
  • Tracking QuickSight resources created outside of the AWS CDK Stack
    • Step 14.1 represents users creating QuickSight resources using the AWS Console and step 14.2 represents that activity getting logged into AWS CloudTrail.
    • Step 14.3 to 14.5 represents triggering EventBridge rule for CloudTrail activities that represents QuickSight resource being created, updated or deleted and then invoke the Asset Tracker REST API to register the QuickSight resource metadata.

Architecture Decisions:

The following are few architecture decisions we took while designing the solution.

  • Choosing Aurora database for Asset Tracker: We have evaluated Amazon Neptune for the Asset Tracker database as most of the metadata information we capture are primarily maintaining relationship between QuickSight resources. But when we looked at the query patterns, we found the query pattern is always just one level deep to find who is the parent of a specific QuickSight resource and that can be solved with a relational database’s Primary Key / Foreign Key relationship and with simple self-join SQL query. Knowing the query pattern does not require a graph database, we decided to go with Amazon Aurora to keep it simple, so that we can avoid introducing a new database technology and can reduce operational overhead of maintaining it. In future as the use case evolve, we can evaluate the need for a Graph database and plan for integrating it. For Amazon Aurora, we choose Amazon Aurora Serverless as the usage pattern is not consistent to reserve a server capacity and the serverless tech stack will help reduce operational overhead.
  • Decoupling Asset Tracker as a common REST API service: The Asset Tracker has future scope to be a centralized metadata layer to keep track of all the QuickSight resources across all business units of Huron. So instead of each business unit having its own metadata database, if we build it as a service and deploy it in a shared AWS service account, then we will get benefit from reduced operational overhead, duplicate infrastructure cost and will be able to get a consolidated view of all assets and their integrations. The service provides the ability of applications to consume metadata about the QuickSight assets and then apply their own mapping of security policies to the assets based on their own application data and access control policies.
  • Central QuickSight account with subfolder for environments: The choice was made to use a central account which reduces developer friction of having multiple accounts with multiple identities, end users having to manage multiple accounts and access to resources. QuickSight folders allow for appropriate permissions for separating “environments”. Furthermore, by using folder-based sharing with QuickSight groups, users with appropriate permissions already have access to the latest versions of QuickSight assets without having to share their individual identities.

The solution included an automated Continuous Integration (CI) and Continuous Deployment (CD) pipeline to deploy the resources from development to staging and then finally to production. The following provides a high-level view of the QuickSight CI/CD deployment strategy.

Aurora Database Tables and Reference Analysis update flow

The following are the database tables integrated to capture the QuickSight resource metadata.

  • QS_Dataset: This captures metadata of all QuickSight datasets that are integrated in the reference analysis or customer analysis. This includes AWS ARN (Amazon Resource Name), data source type, ID and more.
  • QS_Template: This table captures metadata of all QuickSight templates, from which customer analysis and dashboards will be created. This includes AWS ARN, parent reference analysis ID, name, version number and more.
  • QS_Folder: This table captures metadata about QuickSight folders which logically groups different visualizations. This includes AWS ARN, name, and description.
  • QS_Analysis: This table captures metadata of all QuickSight analysis that includes AWS ARN, name, type, dataset IDs, parent template ID, tags, permissions and more.
  • QS_Dashboard: This table captures metadata information of QuickSight dashboards that includes AWS ARN, parent template ID, name, dataset IDs, tags, permissions and more.
  • QS_Folder_Asset_Mapping: This table captures folder to QuickSight asset mapping that includes folder ID, Asset ID, and asset type.

As the solution moves to the next phase of implementation, we plan to introduce additional database tables to capture metadata information about QuickSight sheets and asset mapping to customers and products. We will extend the functionality to support visual based embedding to enable truly integrated customer data experiences where embedded visuals mesh with the native content on a web page.

While explaining the use case, we have highlighted it creates a challenge when a base reference analysis gets updated and we need to track the templates that are inherited from it make sure the change is pushed to the linked customer analysis and dashboards. The following example scenarios explains, how the database tables change when a reference analysis is updated.

Example Scenario: When “reference analysis” is updated with a new release

When a base reference analysis is updated because of a new feature release, then a new QuickSight reference analysis and template needs to be created. Then we need to update all customer analysis and dashboard records to point to the new template ID to form the lineage.

The following sequential steps represent the database changes that needs to happen.

  • Insert a new record to the “Analysis” table to represent the new reference analysis creation.
  • Insert a new record to the “Template” table with new reference analysis ID as parent, created in step 1.
  • Retrieve “Analysis” and “Dashboard” table records that points to previous template ID and then update those records with the new template ID, created in step 2.

How will it enable a more robust embedding experience

The QuickSight asset tracker integration with Huron’s products provide users with a personalized, secure and modern analytics experience. When user’s login through Huron’s online application, it will use logged in user’s information to dynamically identify the products they are mapped to and then render the QuickSight visualizations & dashboards that the user is entitled to see. This will improve user experience, enable granular permission management and will also increase performance.

How AWS collaborated with Huron to help build the solution

AWS team collaborated with Huron team to design and implement the solution. AWS Data Lab Resident Architect collaborated with Huron’s lead architect for initial architecture design that compared different options for integration and deriving tradeoffs between them, before finalizing the final architecture. Then with the help of AWS Professional service engineer, we could build the base solution that can be extended by Huron team to roll it out to all business units and integrate additional reporting features on top of it.

The AWS Data Lab Resident Architect program provides AWS customers with guidance in refining and executing their data strategy and solutions roadmap. Resident Architects are dedicated to customers for 6 months, with opportunities for extension, and help customers (Chief Data Officers, VPs of Data Architecture, and Builders) make informed choices and tradeoffs about accelerating their data and analytics workloads and implementation.

The AWS Professional Services organization is a global team of experts that can help customers realize their desired business outcomes when using the AWS Cloud. The Professional Services team work together with customer’s team and their chosen member of the AWS Partner Network (APN) to execute their enterprise cloud computing initiatives.

Next Steps

Huron has rolled out the solution for one business unit and as a next step we plan to roll it out to all business units, so that the asset tracker service is populated with assets available across all business units of the organization to provide consolidated view.

In addition, Huron will be building a reporting layer on top of the Amazon Aurora asset tracker database, so that the leadership has a way to discover assets by business unit, by owner, created between specific date range or the reports that are not updated since a while.

Once the asset tracker is populated with all QuickSight assets, it will be integrated into the front-end online application that can help end users discover existing assets and request creation of new assets.

Newer QuickSight API’s such as assets-as-a-bundle and assets-as-code further accelerate the capabilities of the service by improving the development velocity and reliability of making changes.

Conclusion

This blog explained how Huron built an Asset Tracker to keep track of all QuickSight resources across the organization. This solution may provide a reference to other organizations who would like to build an inventory of visualization reports, ML models or other technical assets. This solution leveraged Amazon Aurora as the primary database, but if an organization would also like to build a detailed lineage of all the assets to understand how they are interrelated then they can consider integrating Amazon Neptune as an alternate database too.

If you have a similar use case and would like to collaborate with AWS Data Analytics Specialist Architects to brainstorm on the architecture, rapidly prototype it and implement a production ready solution then connect with your AWS Account Manager or AWS Solution Architect to start an engagement with AWS Data Lab team.


About the Authors

Corey Johnson is the Lead Data Architect at Huron, where he leads its data architecture for their Global Products Data and Analytics initiatives.
Sakti Mishra is a Principal Data Analytics Architect at AWS, where he helps customers modernize their data architecture, help define end to end data strategy including data security, accessibility, governance, and more. He is also the author of the book Simplify Big Data Analytics with Amazon EMR. Outside of work, Sakti enjoys learning new technologies, watching movies, and visiting places with family.

How Dafiti made Amazon QuickSight its primary data visualization tool

Post Syndicated from Valdiney Gomes original https://aws.amazon.com/blogs/big-data/how-dafiti-made-amazon-quicksight-its-primary-data-visualization-tool/

This is a guest post by Valdiney Gomes, Hélio Leal, and Flávia Lima from Dafiti.

Data and its various uses is increasingly evident in companies, and each professional has their preferences about which technologies to use to visualize data, which isn’t necessarily in line with the technological needs and infrastructure of a company. At Dafiti, a Brazilian fashion and style e-commerce retailer, it was no different. Five tools were used by different sectors of the company, which caused misalignment and management overhead, spreading our resources thin to support them. Looking for a tool that would enable us to democratize our data, we chose Amazon QuickSight, a cloud-native, serverless business intelligence (BI) service that powers interactive dashboards that lets us make better data-driven decisions, as a corporate solution for data visualization.

In this post, we discuss why we chose QuickSight and how we implemented it.

Why we chose QuickSight

We had specific requirements for our BI solution and looked at many different options. The following factors guided our decision:

  • Tool close to data – It was important to have the data visualization tool as close to the data as possible. At Dafiti, the entire infrastructure is on AWS, and we use Amazon Redshift as our Data Warehouse. QuickSight, when using SPICE (Super-fast, Parallel, In-memory Calculation Engine), extracts data from Amazon Redshift as efficiently as possible using UNLOAD, which optimizes the use of Amazon Redshift.
  • Highly available and accessible solution – We wanted to be able to be access the tool by web or mobile interface, in addition to being able to do almost anything through API calls.
  • Serverless solution – All the other data visualization solutions that were used at Dafiti were on premises, which created unnecessary cost and effort to maintain these services, taking the focus away from what was most important to us: data.
  • Flexible pricing model – We needed a pricing model that would allow us to provide access to everyone in the company and at a price defined by usage and not by license. Thanks to AWS pay-as-you-go pricing, with more than double the number of users we had on our previous main data visualization solution, our cost with QuickSight is about 10 times lower.
  • Robust documentation – The material provided by AWS proved to be helpful, allowing our team to put the project into production.

Unifying our solution

We were previously using Qlikview, Sisense, Tableau, SAP, and Excel to analyze our data across different teams. We were already using other AWS services and learning about QuickSight when we hosted a Data Battle with AWS, a hybrid event for more than 230 Dafiti employees. This event had a hands-on approach with a workshop followed by a friendly QuickSight competition. Participants had to get information in their own dashboard to answer correctly. This 5-hour event flew by, accelerated the learning path of technical and business teams, and proved that QuickSight was the right tool for us.

QuickSight has brought all of our teams into one tool, while lowering costs by 80% and enabling us to do so much more together. Currently, over 400 employees, including our CEO, across nine different business units are using QuickSight as their sole source of truth on a daily basis. This includes human resources, auditing, and customer service, which previously had their analyses spread across several sources.

Data democratization

Data democratization is one of Dafiti’s main objectives. We believe that allowing everyone to analyze the data, following Brazilian, Argentinean, and Colombian privacy laws, unlocks potential for improving decision-making processes by extracting value from the data generated by the company. However, the democratization of data comes with the responsible use of resources. Yes, we want all users to be able to access and extract value from the data, but the cost can never be greater than the value that this generates.

How we organized the project

Data democratization drives Dafiti’s strategy. When implementing QuickSight, the obsession of becoming an even more data-driven company (we talk about this at the AWS Summit SP 2022) and having data increasingly accessible was what guided the project.

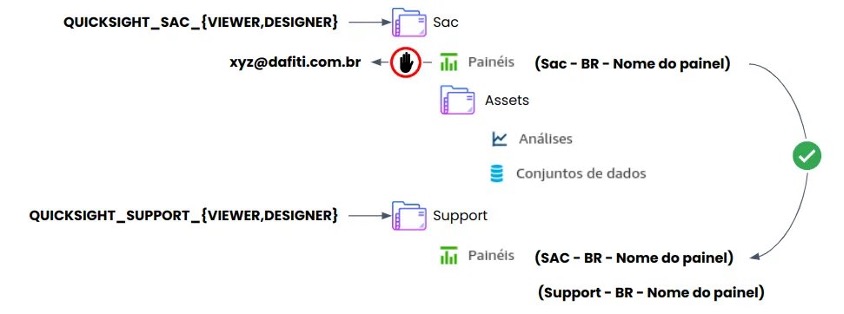
We organized QuickSight by folders, as can be seen in the following figure, and each folder represents a business area. This makes it easier to grant access and ensures that all people from the same area have access to exactly the same set of data and reports.

model of Dafiti's QuickSight folders

In this model, people from the corporate data area can view and edit any resource from any area, while customer service users can view and edit resources only for customer service.

Expanding the model a bit, the reports created by one area can be shared with others, as can be seen in the following figure, in which the SAC report was shared with Support, creating what we call a reporting portfolio.

an expansion of the folders

In this way, all users who join any of the groups will have exactly the same view as any of their peers, eliminating privileges in accessing data. In addition, the portfolio is enriched every day with reports that are created and maintained by other areas, but which may be of interest to areas other than the one responsible for creating it.

For this to work correctly, a certain rigidity is necessary in relation to the few naming and documentation standards that have been defined. On the other hand, designers have complete freedom to define the characteristics of their reports.

Another highlight in this model is that no report can be shared directly with a specific user; this restriction was defined using custom permissions in QuickSight. Therefore, the reports are always shared only through the folders. After all, we want the data to be accessible equally to everyone in the company.

Technical configurations

QuickSight offers a comprehensive API, and all the activities we carry out on a daily basis take place through these APIs. Among these activities, we highlight the granting of access and the monitoring of various aspects of the tool.

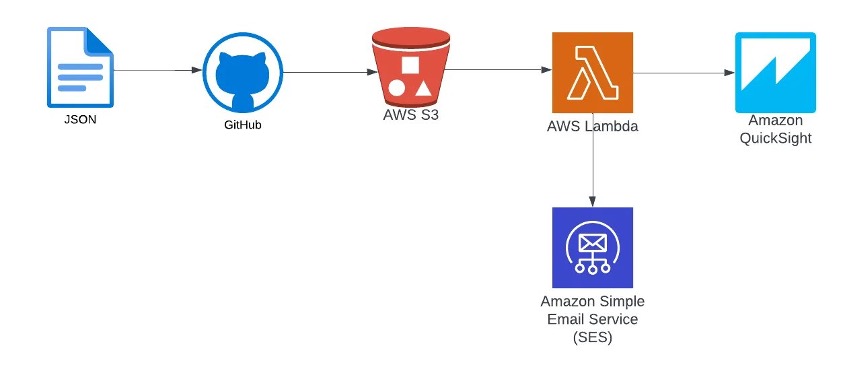
The QuickSight visual interface allows most of the tool’s maintenance activities to be performed and integration with Active Directory or the use of AWS Identity and Access Management (IAM) users is possible, but we understand that it wouldn’t be the ideal choice to grant access. Therefore, we defined an access grant flow for users and groups based on the QuickSight API, as can be seen in the following figure. In this model, the creation and removal of users is done through a JSON file with the following structure:

{
 "Version":"1.0.0",
 "Namespace":"default",
 "AwsAccountId":"<AwsAccountId>",
 "AwsRegion":"<AwsRegion>",
 "Permission":{
  "GroupList":[
   {"GroupName":"QUICKSIGHT_DATA_EDITOR"},
   {"GroupName":"QUICKSIGHT_DATA_VIEWER"},
   {"GroupName":"QUICKSIGHT_DATA_DESIGNER"},
   {"GroupName":"QUICKSIGHT_SAC_VIEWER"},
   {"GroupName":"QUICKSIGHT_SAC_DESIGNER"},
    ...
  ],
  "UserList":[
   {"UserName":"[email protected]","Active":"True","GroupList":[{"GroupName":"QUICKSIGHT_DATA_EDITOR"}]},
   {"UserName":"[email protected]","Active":"True","GroupList":[{"GroupName":"QUICKSIGHT_SAC_VIEWER"}]},
   ...
  ]
 }
}

Whenever a user needs to be added or changed, the file is edited and a pull request is submitted to GitHub. If the request is approved, an action is triggered to send the file to an Amazon Simple Storage Service (Amazon S3) bucket. From this, an AWS Lambda function is triggered that performs two activities: the first is the maintenance of users and groups, and the second is the sending of an invitation through Amazon Simple Email Service (Amazon SES) for users to join QuickSight. In our case, we opted for a personalized invitation model that would emphasize the data democratization initiative that is being conducted.

an architecture diagram from JSON to QuickSight

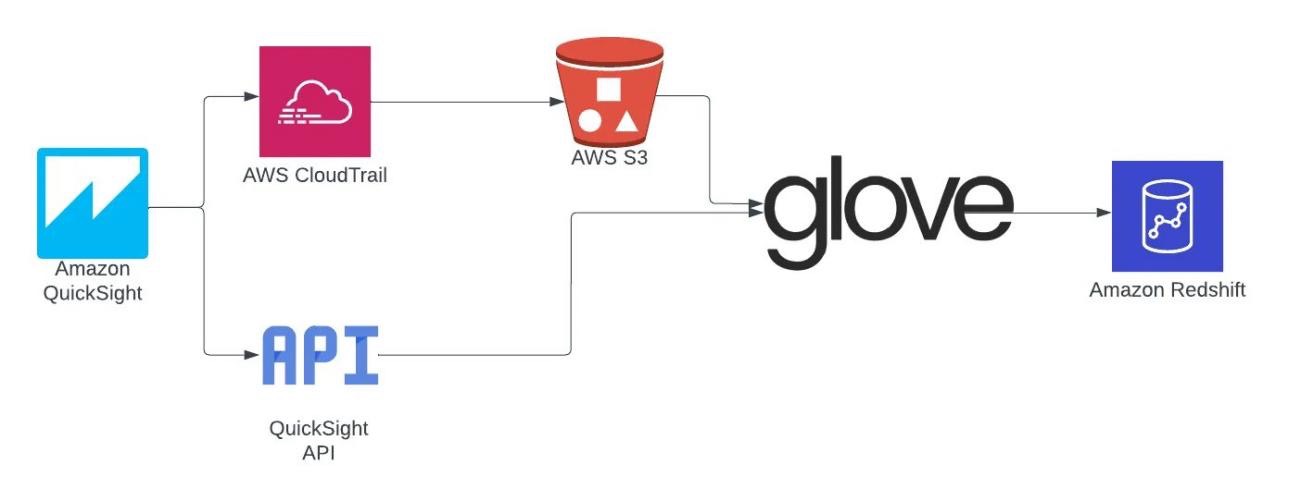
To monitor the tool, we implemented the architecture shown in the following figure, in which we used AWS CloudTrail to pull out the QuickSight logs and the QuickSight API to extract information from the tool’s resources, such as reports, users, datasets, data sources, and more. All of this data is processed by Glove, our data integration tool, stored in Amazon Redshift, and analyzed in QuickSight itself. This allows us to understand the behavior of our users and concentrate efforts on the most-used resources, in addition to allowing optimal cost control and the use of SPICE.

an architecture diagram from QuickSight to Redshift

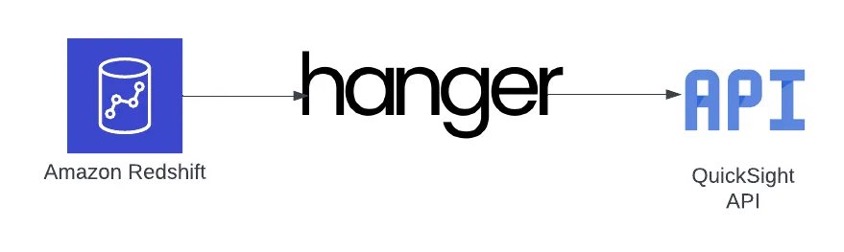
To update the datasets, we don’t use the QuickSight internal scheduler, due to the large volume of data and the complexity of the DAGs. We prefer updating the datasets within our ETL (extract, transform, and load) and ELT process orchestration flow. For this purpose, we use Hanger, our orchestration tool. This approach allows the datasets to be updated only when the data source is changed and the data quality processes are executed. This model is represented by the following figure.

an architecture diagram with Redshift, Hanger, and QuickSight API

Conclusion

Choosing a data visualization tool is not a simple task. It involves many considerations, and several aspects must be analyzed in order for the choice to fit the characteristics of the company and to be consistent with the profile of business users.

For Dafiti, QuickSight was a natural choice from the moment we learned about its features. We needed a service that was in the same cloud as our main data sources, extremely fast using SPICE, and solved the maintenance and cost problem of on-premises applications. In terms of functionalities that are necessary for our business, it met our needs perfectly.

Do you want to know more about what we are doing in the data area here at Dafiti? Check out the following videos:


About the Authors

Valdiney Gomes is Data Engineering Coordinator at Dafiti. He worked for many years in software engineering, migrated to data engineering, and currently leads an amazing team responsible for the data platform for Dafiti in Latin America.
Hélio Leal is a Data Engineering Specialist at Dafiti, responsible for maintaining and evolving the entire data platform at Dafiti using AWS solutions.
Flávia Lima is a Data Engineer at Dafiti, responsible for sustaining the data platform and providing the data from many sources to internal customers.

Mitigating DDoS with data science using AWS Shield Advanced and AWS WAF

Post Syndicated from Jasmine Maheshwari original https://aws.amazon.com/blogs/architecture/mitigating-ddos-with-data-science-using-aws-shield-advanced-and-aws-waf/

This blog post helps customers in mitigating distributed denial-of-service (DDoS) using AWS Shield Advanced, AWS WAF, and data science. We explore how to use these services along with machine learning (ML) to detect and mitigate DDoS attacks.

Bad actors conduct DDoS attacks using botnets. Through botnets, attackers look for zero-day vulnerabilities—specifically on network devices such as routers—and make these devices a part of their network. Bots speared around the world are waiting for instructions from control servers.

This post examines a real-world use case. Online payment solutions company Razorpay has a business-to-business (B2B) model where merchants invoke APIs for payments. Given the complex nature of B2B payments, the traffic patterns between small-scale merchants and large-scale merchants needs to be distinguished. This business model puts the company at risk for DDoS attacks, and here is how AWS helps them address this ongoing concern.

First, we will introduce an initial DDoS architecture approach and then how it was modified to meet specific Razorpay needs, as is possible for cross-industry client with varying requirements.

Basic DDoS recommendations

Let’s explore some out-of-the-box DDoS business solution recommendations for different resource categories:

  • Static websites: Amazon CloudFront is a content delivery network (CDN) service that is used to host static websites. The AWS WAF rate-limiting rule can be used to limit traffic on a CDN.
  • Dynamic websites: In this scenario, a standard WAF Rate Limit rule can be used on Application Load Balancer (ALB).
  • APIs with customer context: APIs receive these assets on behalf of other merchants (for example, an end-user places a food order from a food-delivery application, completes a payment, and the request is sent to api.razorpay.com. Razorpay understands that the end user is trying to make a payment toward the food app).

Figure 1 represents the difficulty levels and solutions for each resource category.

DDoS business solution resource category recommendations

Figure 1. DDoS business solution resource category recommendations

DDoS response phases

We’ve discussed initial DDoS architectures, so now let’s explore the various DDoS response phases:

  • Phase 1 – Automated inventory: Creating an automated inventory system capturing the list of APIs or websites exposed. The APIs are ranked by exposure and risk of an outage to create a list of assets that is ranked on the basis of risk.
  • Phase 2 – Bucketing assets into groups: Bucketing APIs and websites (static or dynamic) into groups. This phase also subgroups the assets into unauthenticated or authenticated, users and more. As we will discuss later in this post, most Razorpay APIs have a customer context requiring a multilayered defense mechanism.
  • Phase 3 – Testing the solution: Simulating attack traffic to test the solution under different loads, origins, and more.

AWS DDoS solutions

AWS has two major out-of-the-box solutions when protecting against DDoS attacks: AWS Shield and AWS WAF.

AWS Shield has three important features for DDoS mitigation:

  1. Alarms: Triggers an alarm when a DDoS attack is suspected, customized based on metrics such as total volume, error rates at the ALB, and response latency
  2. Visibility: Provides top five important field values in real time, such as requesting client IPs, countries, user agents, referrer headers, and url routes to take action.
  3. On-call support: Provides on-call support from the Shield Response team (SRT) to understand attack vectors and create AWS WAF rules based on insights.

AWS WAF has two rule types:

  1. Blocking: Blocks requests matching expected variables, from individuals to a combination of fields such as IP, URL route, body, or country
  2. Rate limiting: Tracks the rate of requests for each originating IP address, and triggers the rule action on IPs with rates that go over the limit. A scope-down statement can also be added to the rule, to only track and rate limit requests that match the scope-down statement. (We will soon discuss how Razorpay relies heavily on rate limiting it the AWS WAF and other microservice architecture solutions.)

Razorpay microservices protection architecture

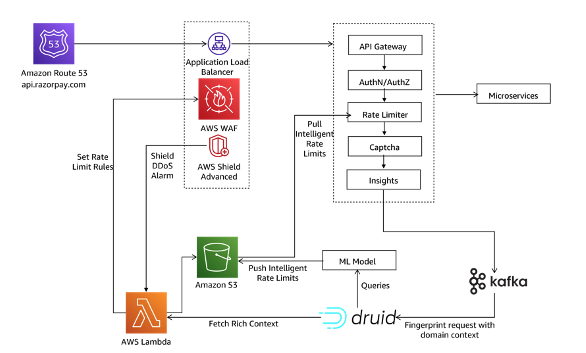
Razorpay has two main layers protecting their internal microservices. The request to payment API api.razorpay.com goes from Amazon Route 53 to ALB. AWS WAF and AWS Shield Advanced are deployed on ALB. Requests are then forwarded to microservices fronted by API Gateway as in Figure 2.

Razorpay’s internal microservices protection layers

Figure 2. Razorpay internal microservices protection layers

Razorpay API Gateway

An API Gateway is a critical piece of infrastructure for microservice architectures. Razorpay is a B2B organization that performs actions on behalf of merchants. To achieve this—and understand context about the merchants and end-users alike—a custom API Gateway:

  • Works at a high scale with very low latency
  • Understands merchant context to provide authentication and authorization
  • Provides security features around malicious traffic

Razorpay uses a self-managed API gateway called Edge. The API Gateway is the first system on the ingress path to understand Razorpay domain context that prior layers cannot. Every request goes through multiple layers of logic at the API Gateway before being forwarded to respective services.

Razorpay Edge and AWS solution insights

As Edge performs multiple computations on each request, Razorpay generates insights for each request to build intelligence and prevent DDoS attacks. These events are fed into a time-series database in near real time and generate insights using machine learning (ML) models. The insights:

  1. Identify malicious patterns: Generating confidence percentage that helps in defining further action, verifies consumer authenticity, and serves the request. It also blocks malicious requests at the edge.
  2. Derive pattern-based rate limits: Deriving rate limits based on a larger set of data—including consumer and IP address—by looking at weekly and monthly patterns.
    Once this information is available at Razorypay Edge, it can perform various operations to ensure only legit requests reach the service layer. Let’s explore the request flow to understand each stage’s contribution toward DDoS handling, as in Figure 3.
Razorpay Edge request flow for DDoS handling

Figure 3. Razorpay Edge request flow for DDoS handling

All Razorpay requests flow through API Gateway. Here are some key recommendations:

  • Based on feedback data available, the gateway checks if the given request pattern falls in the malicious category. If the confidence percentage is high for a malicious request, block the request. A block rule is applied at the AWS WAF layer. If the confidence percentage is low, use CAPTCHA to check user authenticity.
  • Apply rate limit on pre-existing data in the request object using feedback from an ML model.
  • Perform authentication/identification and authorization.
  • Apply rate limit on data derived from request object, also using feedback from a ML model.
  • Request user CAPTCHA verification if the request is identified as malicious with low confidence.

As a best practice, publish generated insights for each request to Apache Kafka out of the request flow to avoid latency impact and reduce blast radius.

Conclusion

In this post, you learned about addressing DDoS attacks with ML models.

Organizations can use the insights data generated by an API Gateway to identify request patterns, categorize the patterns into various buckets, and perform the following depending on category:

  • Send feedback to an API Gateway for immediate action
  • Update the rate limits for Edge-based historical patterns
  • Update WAF rule for blocking/reducing rate limits

As discussed, using AWS WAF and AWS Shield Advanced along with ML helps detect and mitigate DDoS attacks.

Optimizing GPU utilization for AI/ML workloads on Amazon EC2

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/optimizing-gpu-utilization-for-ai-ml-workloads-on-amazon-ec2/

­­­­This blog post is written by Ben Minahan, DevOps Consultant, and Amir Sotoodeh, Machine Learning Engineer.

Machine learning workloads can be costly, and artificial intelligence/machine learning (AI/ML) teams can have a difficult time tracking and maintaining efficient resource utilization. ML workloads often utilize GPUs extensively, so typical application performance metrics such as CPU, memory, and disk usage don’t paint the full picture when it comes to system performance. Additionally, data scientists conduct long-running experiments and model training activities on existing compute instances that fit their unique specifications. Forcing these experiments to be run on newly provisioned infrastructure with proper monitoring systems installed might not be a viable option.

In this post, we describe how to track GPU utilization across all of your AI/ML workloads and enable accurate capacity planning without needing teams to use a custom Amazon Machine Image (AMI) or to re-deploy their existing infrastructure. You can use Amazon CloudWatch to track GPU utilization, and leverage AWS Systems Manager Run Command to install and configure the agent across your existing fleet of GPU-enabled instances.

Overview

First, make sure that your existing Amazon Elastic Compute Cloud (Amazon EC2) instances have the Systems Manager Agent installed, and also have the appropriate level of AWS Identity and Access Management (IAM) permissions to run the Amazon CloudWatch Agent. Next, specify the configuration for the CloudWatch Agent in Systems Manager Parameter Store, and then deploy the CloudWatch Agent to our GPU-enabled EC2 instances. Finally, create a CloudWatch Dashboard to analyze GPU utilization.

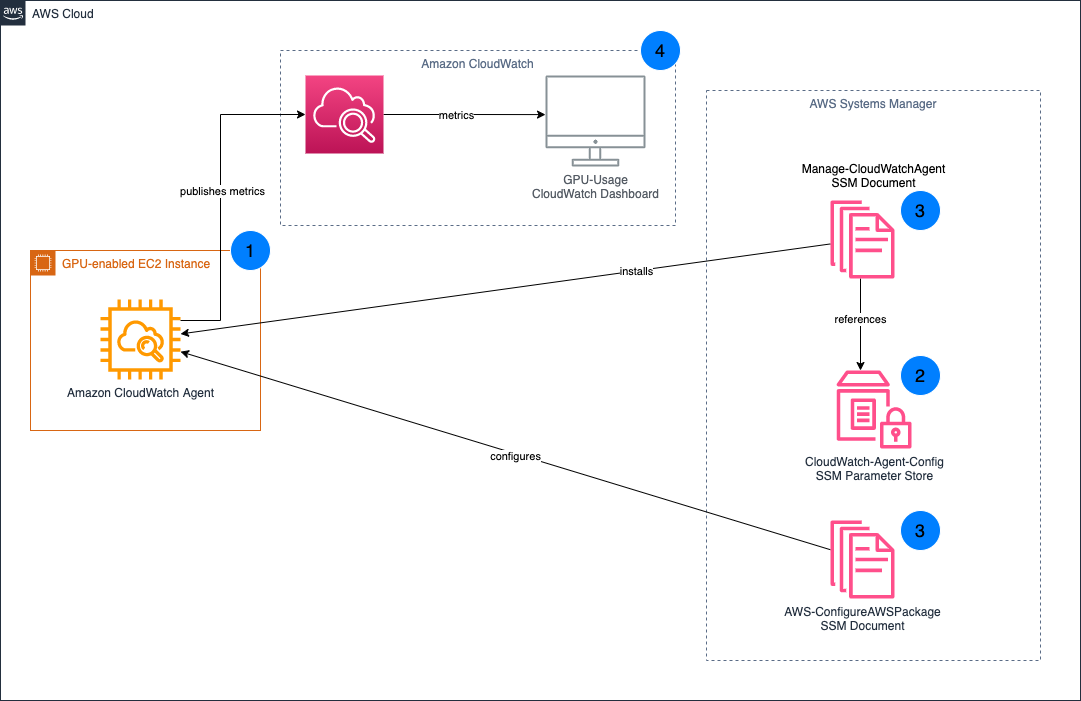
Architecture Diagram depicting the integration between AWS Systems Manager with RunCommand Arguments stored in SSM Parameter Store, your Amazon GPU enabled EC2 instance with installed Amazon CloudWatch Agen­t, and Amazon CloudWatch Dashboard that aggregates and displays the ­reported metrics.

  1. Install the CloudWatch Agent on your existing GPU-enabled EC2 instances.
  2. Your CloudWatch Agent configuration is stored in Systems Manager Parameter Store.
  3. Systems Manager Documents are used to install and configure the CloudWatch Agent on your EC2 instances.
  4. GPU metrics are published to CloudWatch, which you can then visualize through the CloudWatch Dashboard.

Prerequisites

This post assumes you already have GPU-enabled EC2 workloads running in your AWS account. If the EC2 instance doesn’t have any GPUs, then the custom configuration won’t be applied to the CloudWatch Agent. Instead, the default configuration is used. For those instances, leveraging the CloudWatch Agent’s default configuration is better suited for tracking resource utilization.

For the CloudWatch Agent to collect your instance’s GPU metrics, the proper NVIDIA drivers must be installed on your instance. Several AWS official AMIs including the Deep Learning AMI already have these drivers installed. To see a list of AMIs with the NVIDIA drivers pre-installed, and for full installation instructions for Linux-based instances, see Install NVIDIA drivers on Linux instances.

Additionally, deploying and managing the CloudWatch Agent requires the instances to be running. If your instances are currently stopped, then you must start them to follow the instructions outlined in this post.

Preparing your EC2 instances

You utilize Systems Manager to deploy the CloudWatch Agent, so make sure that your EC2 instances have the Systems Manager Agent installed. Many AWS-provided AMIs already have the Systems Manager Agent installed. For a full list of the AMIs which have the Systems Manager Agent pre-installed, see Amazon Machine Images (AMIs) with SSM Agent preinstalled. If your AMI doesn’t have the Systems Manager Agent installed, see Working with SSM Agent for instructions on installing based on your operating system (OS).

Once installed, the CloudWatch Agent needs certain permissions to accept commands from Systems Manager, read Systems Manager Parameter Store entries, and publish metrics to CloudWatch. These permissions are bundled into the managed IAM policies AmazonEC2RoleforSSM, AmazonSSMReadOnlyAccess, and CloudWatchAgentServerPolicy. To create a new IAM role and associated IAM instance profile with these policies attached, you can run the following AWS Command Line Interface (AWS CLI) commands, replacing <REGION_NAME> with your AWS region, and <INSTANCE_ID> with the EC2 Instance ID that you want to associate with the instance profile:

aws iam create-role --role-name CloudWatch-Agent-Role --assume-role-policy-document  '{"Statement":{"Effect":"Allow","Principal":{"Service":"ec2.amazonaws.com"},"Action":"sts:AssumeRole"}}'
aws iam attach-role-policy --role-name CloudWatch-Agent-Role --policy-arn arn:aws:iam::aws:policy/service-role/AmazonEC2RoleforSSM
aws iam attach-role-policy --role-name CloudWatch-Agent-Role --policy-arn arn:aws:iam::aws:policy/AmazonSSMReadOnlyAccess
aws iam attach-role-policy --role-name CloudWatch-Agent-Role --policy-arn arn:aws:iam::aws:policy/CloudWatchAgentServerPolicy
aws iam create-instance-profile --instance-profile-name CloudWatch-Agent-Instance-Profile
aws iam add-role-to-instance-profile --instance-profile-name CloudWatch-Agent-Instance-Profile --role-name CloudWatch-Agent-Role
aws ec2 associate-iam-instance-profile --region <REGION_NAME> --instance-id <INSTANCE_ID> --iam-instance-profile Name=CloudWatch-Agent-Instance-Profile

Alternatively, you can attach the IAM policies to your existing IAM role associated with an existing IAM instance profile.

aws iam attach-role-policy --role-name <ROLE_NAME> --policy-arn arn:aws:iam::aws:policy/service-role/AmazonEC2RoleforSSM
aws iam attach-role-policy --role-name <ROLE_NAME> --policy-arn arn:aws:iam::aws:policy/AmazonSSMReadOnlyAccess
aws iam attach-role-policy --role-name <ROLE_NAME> --policy-arn arn:aws:iam::aws:policy/CloudWatchAgentServerPolicy
aws ec2 associate-iam-instance-profile --region <REGION_NAME> --instance-id <INSTANCE_ID> --iam-instance-profile Name=<INSTANCE_PROFILE>

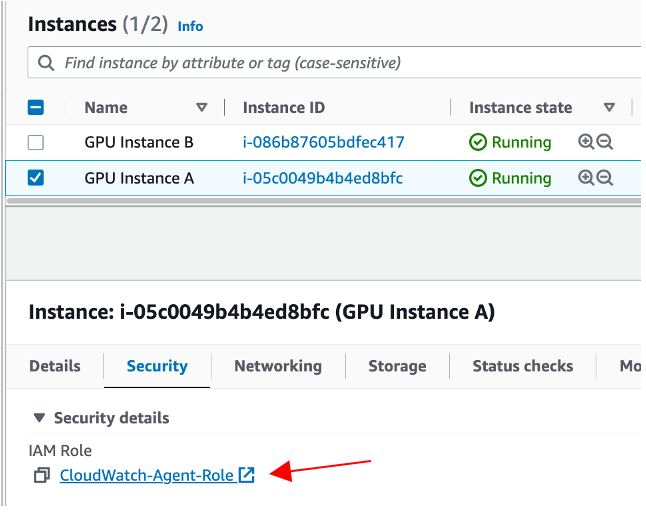
Once complete, you should see that your EC2 instance is associated with the appropriate IAM role.

An Amazon EC2 Instance with the CloudWatch-Agent-Role IAM Role attached

This role should have the AmazonEC2RoleforSSM, AmazonSSMReadOnlyAccess and CloudWatchAgentServerPolicy IAM policies attached.

The CloudWatch-Agent-Role IAM Role’s attached permission policies, Amazon EC2 Role for SSM, CloudWatch Agent Server ¬Policy, and Amazon SSM Read Only Access

Configuring and deploying the CloudWatch Agent

Before deploying the CloudWatch Agent onto our EC2 instances, make sure that those agents are properly configured to collect GPU metrics. To do this, you must create a CloudWatch Agent configuration and store it in Systems Manager Parameter Store.

Copy the following into a file cloudwatch-agent-config.json:

{
    "agent": {
        "metrics_collection_interval": 60,
        "run_as_user": "cwagent"
    },
    "metrics": {
        "aggregation_dimensions": [
            [
                "InstanceId"
            ]
        ],
        "append_dimensions": {
            "AutoScalingGroupName": "${aws:AutoScalingGroupName}",
            "ImageId": "${aws:ImageId}",
            "InstanceId": "${aws:InstanceId}",
            "InstanceType": "${aws:InstanceType}"
        },
        "metrics_collected": {
            "cpu": {
                "measurement": [
                    "cpu_usage_idle",
                    "cpu_usage_iowait",
                    "cpu_usage_user",
                    "cpu_usage_system"
                ],
                "metrics_collection_interval": 60,
                "resources": [
                    "*"
                ],
                "totalcpu": false
            },
            "disk": {
                "measurement": [
                    "used_percent",
                    "inodes_free"
                ],
                "metrics_collection_interval": 60,
                "resources": [
                    "*"
                ]
            },
            "diskio": {
                "measurement": [
                    "io_time"
                ],
                "metrics_collection_interval": 60,
                "resources": [
                    "*"
                ]
            },
            "mem": {
                "measurement": [
                    "mem_used_percent"
                ],
                "metrics_collection_interval": 60
            },
            "swap": {
                "measurement": [
                    "swap_used_percent"
                ],
                "metrics_collection_interval": 60
            },
            "nvidia_gpu": {
                "measurement": [
                    "utilization_gpu",
                    "temperature_gpu",
                    "utilization_memory",
                    "fan_speed",
                    "memory_total",
                    "memory_used",
                    "memory_free",
                    "pcie_link_gen_current",
                    "pcie_link_width_current",
                    "encoder_stats_session_count",
                    "encoder_stats_average_fps",
                    "encoder_stats_average_latency",
                    "clocks_current_graphics",
                    "clocks_current_sm",
                    "clocks_current_memory",
                    "clocks_current_video"
                ],
                "metrics_collection_interval": 60
            }
        }
    }
}

Run the following AWS CLI command to deploy a Systems Manager Parameter CloudWatch-Agent-Config, which contains a minimal agent configuration for GPU metrics collection. Replace <REGION_NAME> with your AWS Region.

aws ssm put-parameter \
--region <REGION_NAME> \
--name CloudWatch-Agent-Config \
--type String \
--value file://cloudwatch-agent-config.json

Now you can see a CloudWatch-Agent-Config parameter in Systems Manager Parameter Store, containing your CloudWatch Agent’s JSON configuration.

CloudWatch-Agent-Config stored in Systems Manager Parameter Store

Next, install the CloudWatch Agent on your EC2 instances. To do this, you can leverage Systems Manager Run Command, specifically the AWS-ConfigureAWSPackage document which automates the CloudWatch Agent installation.

  1. Run the following AWS CLI command, replacing <REGION_NAME> with the Region into which your instances are deployed, and <INSTANCE_ID> with the EC2 Instance ID on which you want to install the CloudWatch Agent.
aws ssm send-command \
--query 'Command.CommandId' \
--region <REGION_NAME> \
--instance-ids <INSTANCE_ID> \
--document-name AWS-ConfigureAWSPackage \
--parameters '{"action":["Install"],"installationType":["In-place update"],"version":["latest"],"name":["AmazonCloudWatchAgent"]}'

2. To monitor the status of your command, use the get-command-invocation AWS CLI command. Replace <COMMAND_ID> with the command ID output from the previous step, <REGION_NAME> with your AWS region, and <INSTANCE_ID> with your EC2 instance ID.

aws ssm get-command-invocation --query Status --region <REGION_NAME> --command-id <COMMAND_ID> --instance-id <INSTANCE_ID>

3.Wait for the command to show the status Success before proceeding.

$ aws ssm send-command \
	 --query 'Command.CommandId' \
    --region us-east-2 \
    --instance-ids i-0123456789abcdef \
    --document-name AWS-ConfigureAWSPackage \
    --parameters '{"action":["Install"],"installationType":["Uninstall and reinstall"],"version":["latest"],"additionalArguments":["{}"],"name":["AmazonCloudWatchAgent"]}'

"5d8419db-9c48-434c-8460-0519640046cf"

$ aws ssm get-command-invocation --query Status --region us-east-2 --command-id 5d8419db-9c48-434c-8460-0519640046cf --instance-id i-0123456789abcdef

"Success"

Repeat this process for all EC2 instances on which you want to install the CloudWatch Agent.

Next, configure the CloudWatch Agent installation. For this, once again leverage Systems Manager Run Command. However, this time the AmazonCloudWatch-ManageAgent document which applies your custom agent configuration is stored in the Systems Manager Parameter Store to your deployed agents.

  1. Run the following AWS CLI command, replacing <REGION_NAME> with the Region into which your instances are deployed, and <INSTANCE_ID> with the EC2 Instance ID on which you want to configure the CloudWatch Agent.
aws ssm send-command \
--query 'Command.CommandId' \
--region <REGION_NAME> \
--instance-ids <INSTANCE_ID> \
--document-name AmazonCloudWatch-ManageAgent \
--parameters '{"action":["configure"],"mode":["ec2"],"optionalConfigurationSource":["ssm"],"optionalConfigurationLocation":["/CloudWatch-Agent-Config"],"optionalRestart":["yes"]}'

2. To monitor the status of your command, utilize the get-command-invocation AWS CLI command. Replace <COMMAND_ID> with the command ID output from the previous step, <REGION_NAME> with your AWS region, and <INSTANCE_ID> with your EC2 instance ID.

aws ssm get-command-invocation --query Status --region <REGION_NAME> --command-id <COMMAND_ID> --instance-id <INSTANCE_ID>

3. Wait for the command to show the status Success before proceeding.

$ aws ssm send-command \
    --query 'Command.CommandId' \
    --region us-east-2 \
    --instance-ids i-0123456789abcdef \
    --document-name AmazonCloudWatch-ManageAgent \
    --parameters '{"action":["configure"],"mode":["ec2"],"optionalConfigurationSource":["ssm"],"optionalConfigurationLocation":["/CloudWatch-Agent-Config"],"optionalRestart":["yes"]}'

"9a4a5c43-0795-4fd3-afed-490873eaca63"

$ aws ssm get-command-invocation --query Status --region us-east-2 --command-id 9a4a5c43-0795-4fd3-afed-490873eaca63 --instance-id i-0123456789abcdef

"Success"

Repeat this process for all EC2 instances on which you want to install the CloudWatch Agent. Once finished, the CloudWatch Agent installation and configuration is complete, and your EC2 instances now report GPU metrics to CloudWatch.

Visualize your instance’s GPU metrics in CloudWatch

Now that your GPU-enabled EC2 Instances are publishing their utilization metrics to CloudWatch, you can visualize and analyze these metrics to better understand your resource utilization patterns.

The GPU metrics collected by the CloudWatch Agent are within the CWAgent namespace. Explore your GPU metrics using the CloudWatch Metrics Explorer, or deploy our provided sample dashboard.

  1. Copy the following into a file, cloudwatch-dashboard.json, replacing instances of <REGION_NAME> with your Region:
{
    "widgets": [
        {
            "height": 10,
            "width": 24,
            "y": 16,
            "x": 0,
            "type": "metric",
            "properties": {
                "metrics": [
                    [{"expression": "SELECT AVG(nvidia_smi_utilization_gpu) FROM SCHEMA(\"CWAgent\", InstanceId) GROUP BY InstanceId","id": "q1"}]
                ],
                "view": "timeSeries",
                "stacked": false,
                "region": "<REGION_NAME>",
                "stat": "Average",
                "period": 300,
                "title": "GPU Core Utilization",
                "yAxis": {
                    "left": {"label": "Percent","max": 100,"min": 0,"showUnits": false}
                }
            }
        },
        {
            "height": 7,
            "width": 8,
            "y": 0,
            "x": 0,
            "type": "metric",
            "properties": {
                "metrics": [
                    [{"expression": "SELECT AVG(nvidia_smi_utilization_gpu) FROM SCHEMA(\"CWAgent\", InstanceId)", "label": "Utilization","id": "q1"}]
                ],
                "view": "gauge",
                "stacked": false,
                "region": "<REGION_NAME>",
                "stat": "Average",
                "period": 300,
                "title": "Average GPU Core Utilization",
                "yAxis": {"left": {"max": 100, "min": 0}
                },
                "liveData": false
            }
        },
        {
            "height": 9,
            "width": 24,
            "y": 7,
            "x": 0,
            "type": "metric",
            "properties": {
                "metrics": [
                    [{ "expression": "SEARCH(' MetricName=\"nvidia_smi_memory_used\" {\"CWAgent\", InstanceId} ', 'Average')", "id": "m1", "visible": false }],
                    [{ "expression": "SEARCH(' MetricName=\"nvidia_smi_memory_total\" {\"CWAgent\", InstanceId} ', 'Average')", "id": "m2", "visible": false }],
                    [{ "expression": "SEARCH(' MetricName=\"mem_used_percent\" {CWAgent, InstanceId} ', 'Average')", "id": "m3", "visible": false }],
                    [{ "expression": "100*AVG(m1)/AVG(m2)", "label": "GPU", "id": "e2", "color": "#17becf" }],
                    [{ "expression": "AVG(m3)", "label": "RAM", "id": "e3" }]
                ],
                "view": "timeSeries",
                "stacked": false,
                "region": "<REGION_NAME>",
                "stat": "Average",
                "period": 300,
                "yAxis": {
                    "left": {"min": 0,"max": 100,"label": "Percent","showUnits": false}
                },
                "title": "Average Memory Utilization"
            }
        },
        {
            "height": 7,
            "width": 8,
            "y": 0,
            "x": 8,
            "type": "metric",
            "properties": {
                "metrics": [
                    [ { "expression": "SEARCH(' MetricName=\"nvidia_smi_memory_used\" {\"CWAgent\", InstanceId} ', 'Average')", "id": "m1", "visible": false } ],
                    [ { "expression": "SEARCH(' MetricName=\"nvidia_smi_memory_total\" {\"CWAgent\", InstanceId} ', 'Average')", "id": "m2", "visible": false } ],
                    [ { "expression": "100*AVG(m1)/AVG(m2)", "label": "Utilization", "id": "e2" } ]
                ],
                "sparkline": true,
                "view": "gauge",
                "region": "<REGION_NAME>",
                "stat": "Average",
                "period": 300,
                "yAxis": {
                    "left": {"min": 0,"max": 100}
                },
                "liveData": false,
                "title": "GPU Memory Utilization"
            }
        }
    ]
}

2. run the following AWS CLI command, replacing <REGION_NAME> with the name of your Region:

aws cloudwatch put-dashboard \
    --region <REGION_NAME> \
    --dashboard-name My-GPU-Usage \
    --dashboard-body file://cloudwatch-dashboard.json

View the My-GPU-Usage CloudWatch dashboard in the CloudWatch console for your AWS region..

An example CloudWatch dashboard, My-GPU-Usage, showing the GPU usage metrics over time.

Cleaning Up

To avoid incurring future costs for resources created by following along in this post, delete the following:

  1. My-GPU-Usage CloudWatch Dashboard
  2. CloudWatch-Agent-Config Systems Manager Parameter
  3. CloudWatch-Agent-Role IAM Role

Conclusion

By following along with this post, you deployed and configured the CloudWatch Agent across your GPU-enabled EC2 instances to track GPU utilization without pausing in-progress experiments and model training. Then, you visualized the GPU utilization of your workloads with a CloudWatch Dashboard to better understand your workload’s GPU usage and make more informed scaling and cost decisions. For other ways that Amazon CloudWatch can improve your organization’s operational insights, see the Amazon CloudWatch documentation.

Alexa Smart Properties creates value for hospitality, senior living, and healthcare properties with Amazon QuickSight Embedded

Post Syndicated from Preet Jassi original https://aws.amazon.com/blogs/big-data/alexa-smart-properties-creates-value-for-hospitality-senior-living-and-healthcare-properties-with-amazon-quicksight-embedded/

This is a guest post by Preet Jassi from Alexa Smart Properties.

Alexa Smart Properties (ASP) is powered by a set of technologies that property owners, property managers, and third-party solution providers can use to deploy and manage Alexa-enabled devices at scale. Alexa can simplify tasks like playing music, controlling lights, or communicating with on-site staff. Our team got its start by building products for hospitality and residential properties, but we have since expanded our products to serve senior living and healthcare properties.

With Alexa now available in hotels, hospitals, senior living homes, and other facilities, we hear stories from our customers every day about how much they love Alexa. Everything from helping veterans with visual impairments gain access to information, to enabling a senior living home resident who had fallen and sustained an injury to immediately alert staff. It’s a great feeling when you can say, “The product I work on every day makes a difference in people’s lives!”

Our team builds the software that leading hospitality, healthcare, and senior living facilities use to manage Alexa devices in their properties. We partner directly with organizations that manage their own properties as well as third-party solution providers to provide comprehensive strategy and deployment support for Alexa devices and skills, making sure that they are ready for end-user customers. Our primary goal is to create value for properties through improved customer satisfaction, cost savings, and incremental revenue. We wanted a way to measure that impact in a fast, efficient, easily accessible way from a return on investment (ROI) perspective.

After we had established what capabilities we needed to close our analytics gap, we got in touch with the Amazon QuickSight team to help. In this post, we discuss our requirements and why Amazon QuickSight Embedded was the right fit for what we needed.

Telling the ROI story with data

As a business-to-business-to-consumer product, our team serves the needs of two customers: the end-users who enjoy Alexa-enabled devices at the properties, and the property managers or solution providers that manage the Alexa deployment. We needed to prove to the latter group of customers that deploying Alexa would not only help them delight their customers, but save money as well.

We had the data necessary to tell that ROI story, but we needed an analytics solution that would allow us to provide insights that can be communicated to leadership.

These were our requirements:

  • Embeddable dashboards – We wanted to embed analytics into our Alexa Smart Properties management console, used by both enterprise customers and solution providers. With QuickSight, dashboards are embedded for aggregated Alexa usage analytics.
  • Easy access to insights – We wanted a tool that was accessible to all of our customers, whether they had a technical background or not. QuickSight provides a beautiful, user-friendly user interface (UI) that our customers can use to interpret their data and analytics.
  • Customizable and rich visuals – Our customers needed to be able to dive deep. QuickSight allows you to drill down into the data to easily create and change whatever visuals you need. Our customers love the look of the visuals and how easy it is to share them with their customers.

Analytics drive engagement

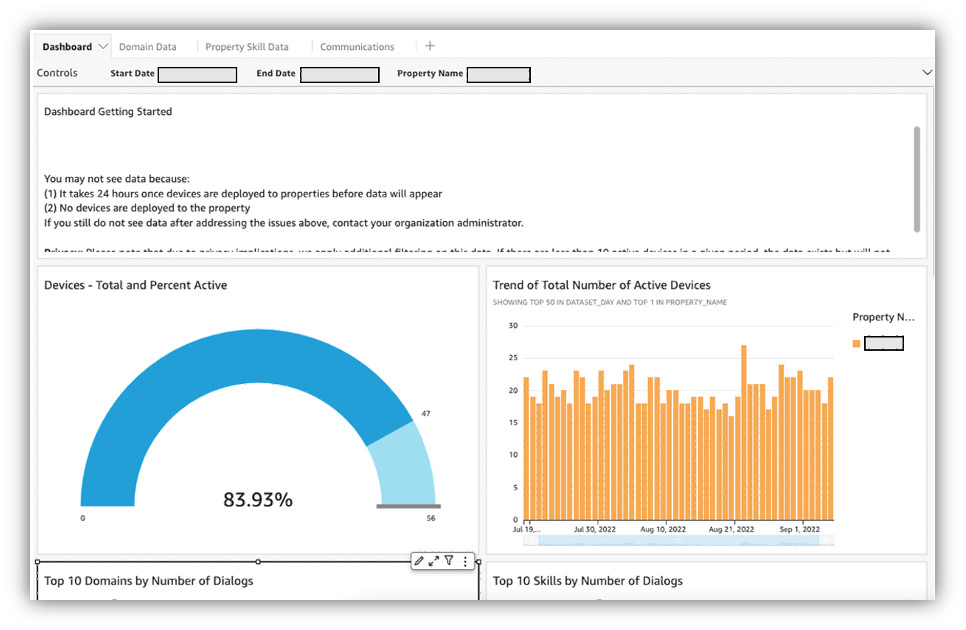
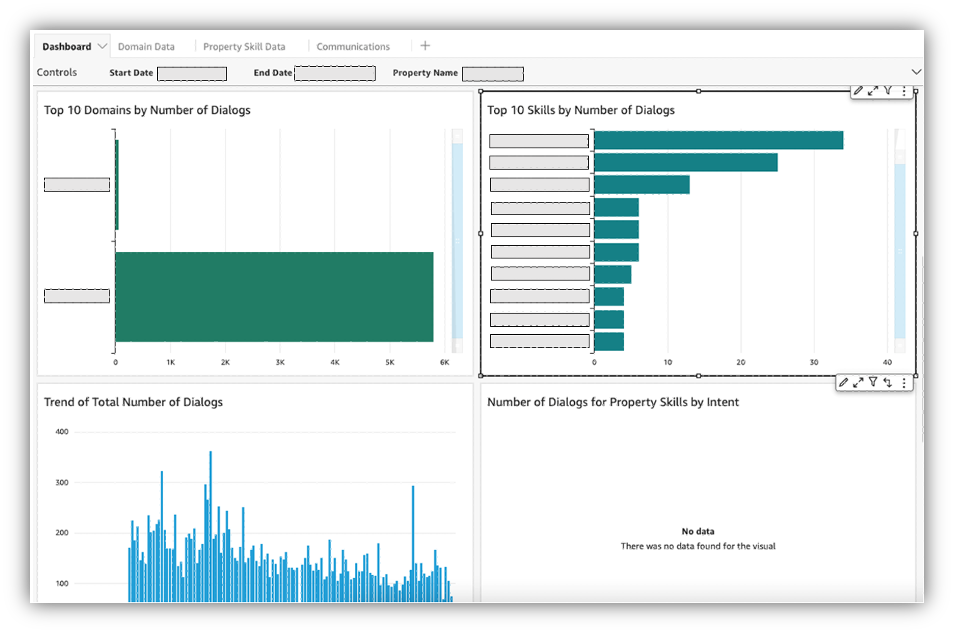
With QuickSight, we can now show detailed device usage information, including quantity and frequency, with insights that connect the dots between that engagement and cost savings. For example, property managers can look at total dialog counts to determine that their guests are using Alexa often, which validates their investment.

The following screenshots show an example of the dashboard our solution providers can access, which they can use to send reports to staff at the properties they serve.

Active devices dashboard

Dialogs dashboard

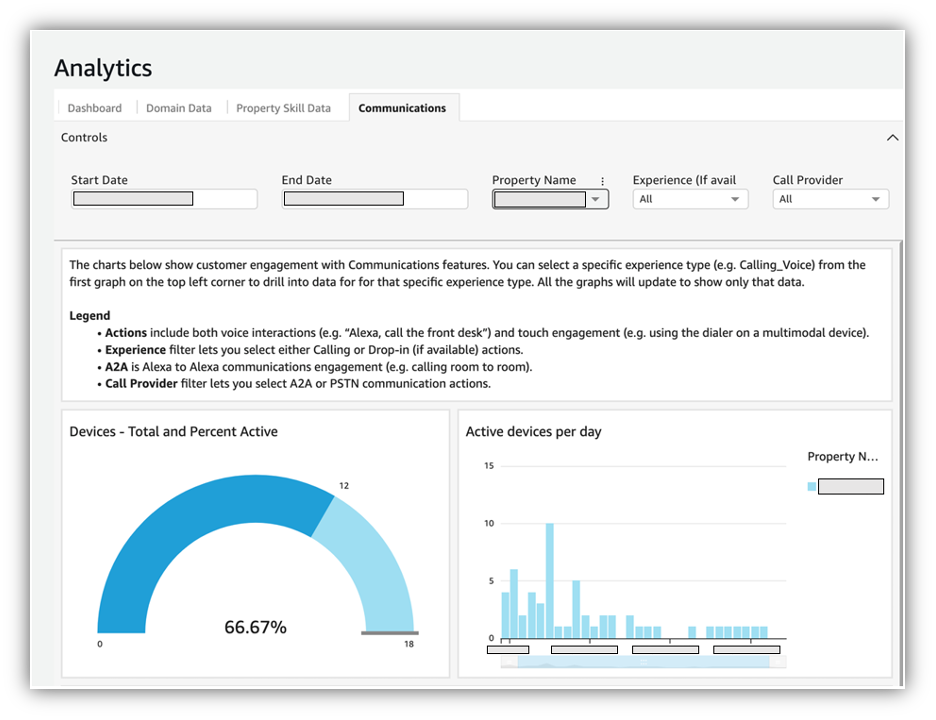
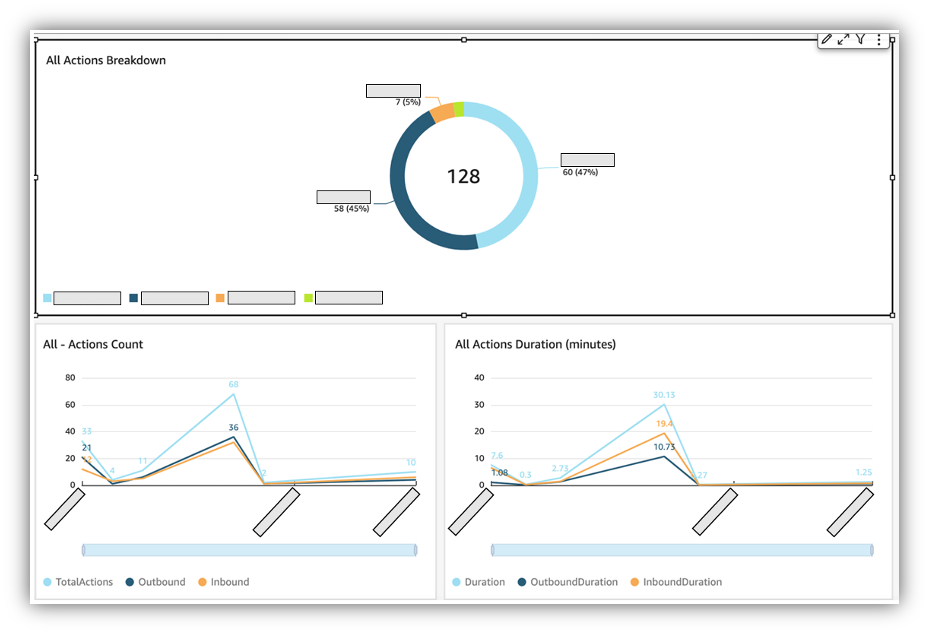
The following screenshots show an example of the Communications tab, which shows how properties use communications features to save costs (both in terms of time and equipment). Customers save time and money on protective equipment by using Alexa’s remote communication features, which enable caretakers to virtually check in on patients instead of visiting a property in person. These metrics help our customers calculate the cost savings from using Alexa.

Communications tab of analytics dashboard

All actions dashboard

In the last year, the Analytics page in our management console has had over 20,000 page views from customers who are accessing the data and insights there to understand the impact Alexa has had on their businesses.

Insights validate investment

With QuickSight embedded dashboards, our direct-property customers and solution providers now have an easy-to-understand visual representation of how Alexa is making a difference for the guests and patients at each property. Embedded dashboards simplify the viewing, analyzing, and insight gathering for key usage metrics that help both enterprise property owners and solution providers connect the dots between Alexa’s use and money saved. Because we use Amazon Redshift to house our data, QuickSight’s seamless integration made it a fantastic choice.

Going forward, we plan to expand and improve upon the analytics foundation we’ve built with QuickSight by providing programmatic access to data—for example, a CSV file that can be sent to a customer’s Amazon Simple Storage Service (Amazon S3) bucket—as well as adding more data to our dashboards, thereby creating new opportunities for deeper insights.

To learn more about how you can embed customized data visuals, interactive dashboards, and natural language querying into any application, visit Amazon QuickSight Embedded.


About the Author

Preet Jassi is a Principal Product Manager Technical with Alexa Smart Properties. Preet fell in love with technology in Grade 5 where he built his first website for his elementary school. Prior to completing his MBA at Cornell, Preet was a UI Team Lead with over 6 years of experience as a software engineer post BSc. Preet’s passion is combining his love of technology (specifically analytics and artificial intelligence), with design, and business strategy to build products that customers love, spending time with family, and keeping active. He currently manages the Developer Experience for Alexa Smart Properties focusing on making it quick and easy to deploy Alexa devices in properties and he loves hearing quotes from end customers on how Alexa has changed their lives.

How CyberSolutions built a scalable data pipeline using Amazon EMR Serverless and the AWS Data Lab

Post Syndicated from Constantin Scoarță original https://aws.amazon.com/blogs/big-data/how-cybersolutions-built-a-scalable-data-pipeline-using-amazon-emr-serverless-and-the-aws-data-lab/

This post is co-written by Constantin Scoarță and Horațiu Măiereanu from CyberSolutions Tech.

CyberSolutions is one of the leading ecommerce enablers in Germany. We design, implement, maintain, and optimize award-winning ecommerce platforms end to end. Our solutions are based on best-in-class software like SAP Hybris and Adobe Experience Manager, and complemented by unique services that help automate the pricing and sourcing processes.

We have built data pipelines to process, aggregate, and clean our data for our forecasting service. With the growing interest in our services, we wanted to scale our batch-based data pipeline to process more historical data on a daily basis and yet remain performant, cost-efficient, and predictable. To meet our requirements, we have been exploring the use of Amazon EMR Serverless as a potential solution.

To accelerate our initiative, we worked with the AWS Data Lab team. They offer joint engineering engagements between customers and AWS technical resources to create tangible deliverables that accelerate data and analytics initiatives. We chose to work through a Build Lab, which is a 2–5-day intensive build with a technical customer team.

In this post, we share how we engaged with the AWS Data Lab program to build a scalable and performant data pipeline using EMR Serverless.

Use case

Our forecasting and recommendation algorithm is fed with historical data, which needs to be curated, cleaned, and aggregated. Our solution was based on AWS Glue workflows orchestrating a set of AWS Glue jobs, which worked fine for our requirements. However, as our use case developed, it required more computations and bigger datasets, resulting into unpredictable performance and cost.

This pipeline performs daily extracts from our data warehouse and a few other systems, curates the data, and does some aggregations (such as daily average). Those will be consumed by our internal tools and generate recommendations accordingly. Prior to the engagement, the pipeline was processing 28 days’ worth of historical data in approximately 70 minutes. We wanted to extend that to 100 days and 365 days of data without having to extend the extraction window or factor in the resources configured.

Solution overview

While working with the Data Lab team, we decided to structure our efforts into two approaches. As a short-term improvement, we were looking into optimizing the existing pipeline based on AWS Glue extract, transform, and load (ETL) jobs, orchestrated via AWS Glue workflows. However, for the mid-term to long-term, we looked at EMR Serverless to run our forecasting data pipeline.

EMR Serverless is an option in Amazon EMR that makes it easy and cost-effective for data engineers and analysts to run petabyte-scale data analytics in the cloud. With EMR Serverless, we could run applications built using open-source frameworks such as Apache Spark (as in our case) without having to configure, manage, optimize, or secure clusters. The following factors influenced our decision to use EMR Serverless:

  • Our pipeline had minimal dependency on the AWS Glue context and its features, instead running native Apache Spark
  • EMR Serverless offers configurable drivers and workers
  • With EMR Serverless, we were able to take advantage of its cost tracking feature for applications
  • The need for managing our own Spark History Server was eliminated because EMR Serverless automatically creates a monitoring Spark UI for each job

Therefore, we planned the lab activities to be categorized as follows:

  • Improve the existing code to be more performant and scalable
  • Create an EMR Serverless application and adapt the pipeline
  • Run the entire pipeline with different date intervals

The following solution architecture depicts the high-level components we worked with during the Build Lab.

In the following sections, we dive into the lab implementation in more detail.

Improve the existing code

After examining our code decisions, we identified a step in our pipeline that consumed the most time and resources, and we decided to focus on improving it. Our target job for this optimization was the “Create Moving Average” job, which involves computing various aggregations such as averages, medians, and sums on a moving window. Initially, this step took around 4.7 minutes to process an interval of 28 days. However, running the job for larger datasets proved to be challenging – it didn’t scale well and even resulted in errors in some cases.

While reviewing our code, we focused on several areas, including checking data frames at certain steps to ensure that they contained content before proceeding. Initially, we used the count() API to achieve this, but we discovered that head() was a better alternative because it returns the first n rows only and is faster than count() for large input data. With this change, we were able to save around 15 seconds when processing 28 days’ worth of data. Additionally, we optimized our output writing by using coalesce() instead of repartition().

These changes managed to shave off some time, down to 4 minutes per run. However, we could achieve a better performance by using cache() on data frames before performing the aggregations, which materializes the data frame upon the following transformation. Additionally, we used unpersist() to free up executors’ memory after we were done with the mentioned aggregations. This led to a runtime of approximately 3.5 minutes for this job.

Following the successful code improvements, we managed to extend the data input to 100 days, 1 year, and 3 years. For this specific job, the coalesce() function wasn’t avoiding the shuffle operation and caused uneven data distribution per executor, so we switched back to repartition() for this job. By the end, we managed to get successful runs in 4.7, 12, and 57 minutes, using the same number of workers in AWS Glue (10 standard workers).

Adapt code to EMR Serverless

To observe if running the same job in EMR Serverless would yield better results, we configured an application that uses a comparable number of executors as in AWS Glue jobs. In the job configurations, we used 2 cores and 6 GB of memory for the driver and 20 executors with 4 cores and 16 GB of memory. However, we didn’t use additional ephemeral storage (by default, workers come with free 20 GB).

By the time we had the Build Lab, AWS Glue supported Apache Spark 3.1.1; however, we opted to use Spark 3.2.0 (Amazon EMR version 6.6.0) instead. Additionally, during the Build Lab, only x86_64 EMR Serverless applications were available, although it now also supports arm64-based architecture.

We adapted the code utilizing AWS Glue context to work with native Apache Spark. For instance, we needed to overwrite existing partitions and sync updates with the AWS Glue Data Catalog, especially when old partitions were replaced and new ones were added. We achieved this by setting spark.conf.set("spark.sql.sources.partitionOverwriteMode", "DYNAMIC") and using an MSCK REPAIR query to sync the relevant table. Similarly, we replaced the read and write operations to rely on Apache Spark APIs.

During the tests, we intentionally disabled the fine-grained auto scaling feature of EMR Serverless while running jobs, in order to observe how the code would perform with the same number of workers but different date intervals. We achieved that by setting spark.dynamicAllocation.enabled to disabled (the default is true).

For the same code, number of workers, and data inputs, we managed to get better performance results with EMR Serverless, which were 2.5, 2.9, 6, and 16 minutes for 28 days, 100 days, 1 year, and 3 years, respectively.

Run the entire pipeline with different date intervals

Because the code for our jobs was implemented in a modular fashion, we were able to quickly test all of them with EMR Serverless and then link them together to orchestrate the pipeline via Amazon Managed Workflows for Apache Airflow (Amazon MWAA).

Regarding performance, our previous pipeline using AWS Glue took around 70 minutes to run with our regular workload. However, our new pipeline, powered by Amazon MWAA-backed EMR Serverless, achieved similar results in approximately 60 minutes. Although this is a notable improvement, the most significant benefit was our ability to scale up to process larger amounts of data using the same number of workers. For instance, processing 1 year’s worth of data only took around 107 minutes to complete.

Conclusion and key takeaways

In this post, we outlined the approach taken by the CyberSolutions team in conjunction with the AWS Data Lab to create a high-performing and scalable demand forecasting pipeline. By using optimized Apache Spark jobs on customizable EMR Serverless workers, we were able to surpass the performance of our previous workflow. Specifically, the new setup resulted in 50–72% better performance for most jobs when processing 100 days of data, resulting in an overall cost savings of around 38%.

EMR Serverless applications’ features helped us have better control over cost. For example, we configured the pre-initialized capacity, which resulted in job start times of 1–4 seconds. And we set up the application behavior to start with the first submitted job and automatically stop after a configurable idle time.

As a next step, we are actively testing AWS Graviton2-based EMR applications, which come with more performance gains and lower cost.


About the Authors

 Constantin Scoarță is a Software Engineer at CyberSolutions Tech. He is mainly focused on building data cleaning and forecasting pipelines. In his spare time, he enjoys hiking, cycling, and skiing.
Horațiu Măiereanu is the Head of Python Development at CyberSolutions Tech. His team builds smart microservices for ecommerce retailers to help them improve and automate their workloads. In his free time, he likes hiking and traveling with his family and friends.
Ahmed Ewis is a Solutions Architect at the AWS Data Lab. He helps AWS customers design and build scalable data platforms using AWS database and analytics services. Outside of work, Ahmed enjoys playing with his child and cooking.
Streaming Android games from cloud to mobile with AWS Graviton-based Amazon EC2 G5g instances

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/streaming-android-games-from-cloud-to-mobile-with-aws-graviton-based-amazon-ec2-g5g-instances/

This blog post is written by Vincent Wang, GCR EC2 Specialist SA, Compute.

Streaming games from the cloud to mobile devices is an emerging technology that allows less powerful and less expensive devices to play high-quality games with lower battery consumption and less storage capacity. This technology enables a wider audience to enjoy high-end gaming experiences from their existing devices, such as smartphones, tablets, and smart TVs.

To load games for streaming on AWS, it’s necessary to use Android environments that can utilize GPU acceleration for graphics rendering and optimize for network latency. Cloud-native products, such as the Anbox Cloud Appliance or Genymotion available on the AWS Marketplace, can provide a cost-effective containerized solution for game streaming workloads on Amazon Elastic Compute Cloud (Amazon EC2).

For example, Anbox Cloud’s virtual device infrastructure can run games with low latency and high frame rates. When combined with the AWS Graviton-based Amazon EC2 G5g instances, which offer a cost reduction of up to 30% per-game stream per-hour compared to x86-based GPU instances, it enables companies to serve millions of customers in a cost-efficient manner.

In this post, we chose the Anbox Cloud Appliance to demonstrate how you can use it to stream a resource-demanding game called Genshin Impact. We use a G5g instance along with a mobile phone to run the streamed game inside of a Firefox browser application.

Overview

Graviton-based instances utilize fewer compute resources than x86-based instances due to the 64-bit architecture of Arm processors used in AWS Graviton servers. As shown in the following diagram, Graviton instances eliminate the need for cross-compilation or Android emulation. This simplifies development efforts and reduces time-to-market, thereby lowering the cost-per-stream. With G5g instances, customers can now run their Android games natively, encode CPU or GPU-rendered graphics, and stream the game over the network to multiple mobile devices.

Architecture difference when running Android on X86-based instance and Graviton-based instance.

Figure 1: Architecture difference when running Android on X86-based instance and Graviton-based instance.

Real-time ray-traced rendering is required for most modern games to deliver photorealistic objects and environments with physically accurate shadows, reflections, and refractions. The G5g instance, which is powered by AWS Graviton2 processors and NVIDIA T4G Tensor Core GPUs, provides a cost-effective solution for running these resource-intensive games.

Architecture

Architecture of Android Streaming Game.

Figure 2: Architecture of Android Streaming Game.

When streaming games from a mobile device, only input data (touchscreen, audio, etc.) is sent over the network to the game streaming server hosted on a G5g instance. Then, the input is directed to the appropriate Android container designated for that particular client. The game application running in the container processes the input and updates the game state accordingly. Then, the resulting rendered image frames are sent back to the mobile device for display on the screen. In certain games, such as multiplayer games, the streaming server must communicate with external game servers to reflect the full game state. In these cases, additional data is transferred to and from game servers and back to the mobile client. The communication between clients and the streaming server is performed using the WebRTC network protocol to minimize latency and make sure that users’ gaming experience isn’t affected.

The Graviton processor handles compute-intensive tasks, such as the Android runtime and I/O transactions on the streaming server. However, for resource-demanding games, the Nvidia GPU is utilized for graphics rendering. To scale effortlessly, the Anbox Cloud software can be utilized to manage and execute several game sessions on the same instance.

Prerequisites

First, you need an Ubuntu single sign-on (SSO) account. If you don’t have one yet, you may create one from Ubuntu One website. Then you need an Android mobile phone with Firefox or Chrome browser installed to play the streaming games.

Setup

We can install Anbox Cloud Appliance in the AWS Marketplace. Select the Arm variant so that it works on Graviton-based instances. If the subscription doesn’t work on the first try, then you receive an email which guides you to a page where you can try again.

Figure 3: Subscribe Anbox Cloud Appliance in AWS Marketplace.

Figure 3: Subscribe Anbox Cloud Appliance in AWS Marketplace.

In this demonstration, we select G5g.xlarge in the Instance type section and leave all settings with default values, except the storage as per the following:

  1. A root disk with minimum 50 GB (required)
  2. An additional Amazon Elastic Block Store (Amazon EBS) volume with at least 100 GB (recommended)

For the Genshin Impact demo, we recommend a specific amount of storage. However, when deploying your Android applications, you must select an appropriate storage size based on the package size. Additionally, you should choose an instance size based on the resources that you plan to utilize for your gaming sessions, such as CPU, memory, and networking. In our demo, we launched only one session from a single mobile device.

Launch the instance and wait until it reaches running status. Then you can secure shell (SSH) to the instance to configure the Android environment.

Install Anbox cloud

To make sure of the security and reliability of some of the package repositories used, we update the CUDA Linux GPG Repository Key. View this Nvidia blog post for more details on this procedure.

$ sudo apt-key del 7fa2af80

$ wget

https://developer.download.nvidia.com/compute/cuda/repos/ubuntu2004/sbsa/cuda keyring_1.0-1_all.deb

$ sudo dpkg -i cuda-keyring_1.0-1_all.deb

As the Android in Anbox Cloud Appliance is running in an LXD container environment, upgrade LXD to the latest version.

  $ sudo snap refresh –channel=5.0/stable lxd

Install the Anbox Cloud Appliance software using the following command and selecting the default answers:

  $ sudo anbox-cloud-appliance init

Watch the status page at https://$(ec2_public_DNS_name) for progress information.

Figure 4: The status of deploying Anbox Cloud.

Figure 4: The status of deploying Anbox Cloud.

The initialization process takes approximately 20 minutes. After it’s complete, register the Ubuntu SSO account previously created, then follow the instructions provided to finalize the process.

  $ anbox-cloud-appliance dashboard register <your Ubuntu SSO email address>

Stream an Android game application

Use the sample from the following repo to setup the service on the streaming server:

  $ git clone https://github.com/anbox-cloud/cloud-gaming-demo.git

Build the Flutter web UI:

$ sudo snap install flutter –classic

$ cd cloud-gaming-demo/ui && flutter build web && cd ..

$ mkdir -p backend/service/static

$ cp -av ui/build/web/* backend/service/static

Then build the backend service which processes requests and interacts with the Anbox Stream Gateway to create instances of game applications. Start by preparing the environment:

$ sudo apt-get install python3-pip

$ sudo pip3 install virtualenv

$ cd backend && virtualenv venv

Create the configuration file for the backend service so that it can access the Anbox Stream Gateway. There are two parameters to set: gateway-URL and gateway-token. The gateway token can be obtained from the following command:

$ anbox-cloud-appliance gateway account create <account-name>

Create a file called config.yaml that contains the two values:

gateway-url: https:// <EC2 public DNS name>

gateway-token: <gateway_token>

Add the following line to the activate hook in the backend/venv/bin/ directory so that the backend service can read config.yaml on its startup:

$ export CONFIG_PATH=<path_to_config_yaml>

Now we can launch the backend service which will be served by default on TCP port 8002.

$./run.sh

In the next steps, we download a game and build it via Anbox Cloud. We need an Android APK and a configuration file. Create a folder under the HOME directory and create a manifest.yaml file in the folder. In this example, we must add the following details in the file. You can refer to the Anbox Cloud documentation for more information on the format.

name: genshin

instance-type: g10.3

resources:

cpus: 10

memory: 25GB

disk-size: 50GB

gpu-slots: 15

features: [“enable_virtual_keyboard”]

Select an APK for the arm64-v8a architecture which is natively supported on Graviton. In this example, we download Genshin Impact, an action role-playing game developed and published by miHoYo. You must supply your own Android APK if you want to try these steps. Download the APK into the folder and rename it to app.apk. Overall, the final layout of the game folder should look as follows:

.

├── app.apk

└── manifest.yaml

Run the following command from the folder to create the application:

$ amc application create  .

Wait until the application status changes to ready. You can monitor the status with the following command:

$ amc application ls

Edit the following:

  1. Update the gameids variable defined in the ui/lib/homepage.dart file to include the name of the game (as declared in the manifest file).
  2. Insert a new key/value pair to the static appNameMap and appDesMap variables defined in the lib/api/application.dart file.
  3. Provide a screenshot of the game (in jpeg format), rename it to <game-name>.jpeg, and put it into the ui/lib/assets directory.

Then, re-build the web UI, copy the contents from the ui/build/web folder to the backend/service/static directory, and refresh the webpage.

Test the game

Using your mobile phone, open the Firefox browser or another browser that supports WebRTC. Type the public DNS name of the G5g instance with the 8002 TCP port, and you should see something similar to the following:

Figure 5: The webpage of the Android streaming game portal.

Figure 5: The webpage of the Android streaming game portal.

Select the Play now button, wait a moment for the application to be setup on the server side, and then enjoy the game.

Figure 6: The screen capture of playing Android streaming game.

Figure 6: The screen capture of playing Android streaming game.

Clean-up

Please cancel the subscription of the Anbox Cloud Appliance in the AWS Marketplace, you can follow the AWS Marketplace Buyer Guide for more details, then terminate the G5g.xlarge instance to avoid incurring future costs.

Conclusion

In this post, we demonstrated how a resource-intensive Android game runs natively on a Graviton-based G5g instance and is streamed to an Arm-based mobile device. The benefits include better price-performance, reduced development effort, and faster time-to-market. One way to run your games efficiently on the cloud is through software available on the AWS Marketplace, such as the Anbox Cloud Appliance, which was showcased as an example method.

To learn more about AWS Graviton, visit the official product page and the technical guide.

SANS Institute uses Amazon QuickSight to drive transformational security awareness maturity within organizations

Post Syndicated from Carl R. Marrelli original https://aws.amazon.com/blogs/big-data/sans-institute-uses-amazon-quicksight-to-drive-transformational-security-awareness-maturity-within-organizations/

This is a guest post by Carl Marrelli from SANS Institute.

The SANS Institute is a world leader in cybersecurity training and certification. For over 30 years, SANS has worked with leading organizations to help ensure security across their organization, as well as with individual IT professionals who want to build and grow their security careers. We partner with over 500 organizations and support over 200,000 IT professionals with more than 90 technical training courses and over 40 professional (GIAC) certifications.

Our Security Awareness products include more than 70 instructional modules and have been deployed to over 6.5 million end-users to bring cybersecurity training to each employee within an organization.

As the Security Awareness department in particular began developing product strategies to deliver data-driven insights to customers, we were clear on using existing analytics services to rapidly build customer-facing analytics solutions. Building on a proven cloud provider would allow us to focus on our core expertise of helping organizations train, learn, and mature their programs instead of spending extra time and resources building and maintaining analytics from scratch.

We identified Amazon QuickSight, a fully managed, cloud-native business intelligence (BI) service, as the product that fit all our criteria. With it, we found an intuitive product with rich visualizations that we could build and grow with rapidly, allowing us to innovate without monetary risks or being locked in to cumbersome contracts. We considered other options, but they couldn’t support the licensing model that fit our needs.

In this post, we go over how we use QuickSight to serve our security customers.

Helping manage human risk with data-driven insights

SANS Security Awareness helps organizations use best-in-class security awareness and training solutions to transform their ability to measure and manage human risk. Security awareness programs are initiatives aimed at educating individuals about the importance of information security and the best practices for maintaining the confidentiality, integrity, and availability of information. We deliver expertly authored training materials to organizations, including computer-based video training sessions, interactive learning modules, supplemental materials, and reinforcement curriculum to keep security top-of-mind for all employees.

As organizations rapidly adopt and expand their use of digital technologies in their day-to-day work, the number of touchpoints with humans increases. As threat landscapes become increasingly more severe, managing human risk is critical to the success of the security program in any organization. Not only do organizations have to conduct security awareness training programs, but they also need insights into data and metrics that identify points of weakness to take data-driven corrective courses of action. As a leader in the space, we wanted to innovate by bringing relevant data-driven insights to our Security Awareness partners and customers in the journey to ensuring human-centered security across their organizations.

New data products to enhance and gamify risk assessment

We built one of our first insights products to support our Behavioral Risk Assessment. This service allows senior security and risk leaders to assess human risk with data handling, digital behavior, and compliance in an organization by individual, team, geography, business unit, and more. Leaders use the assessment to mature their security awareness capability with risk-informed interventions, identify process and procedure gaps, surface shadow IT, and reduce overall awareness training costs by focusing attention on the most important areas of risk.

Behavioral Risk Assessment dashboard with various charts

Delivered via a survey customized to the data types and risk profile of an organization, this assessment allows risk management leaders to more easily understand the data handling practices across roles and departments. Dashboards built in QuickSight empower stakeholders to quickly visualize what areas may need added attention by way of training intervention or updated policy.

Another product area where we invested in analytics to help organizations identify human risk is in gamified awareness training. The SANS Scavenger Hunt utilizes QuickSight in a unique way as a real-time game scoreboard. Players compete in the hunt while solving cybersecurity-related challenges, giving security teams a fun way to engage the workforce and promote good cyber behaviors.

Security Awareness challenge dashboard

The Scavenger Hunt was widely deployed during global Cybersecurity Awareness Month—a time for security awareness practitioners to shine a light on the purpose and mission of security awareness and also have a little fun. Typically, programs run during this time take place outside any regulated training cycle and are typically not delivered as mandatory training. This being the case, we identified dashboards as a way to gamify the experience to increase engagement among participants. These dashboards, built using QuickSight, provided users access to a leaderboard to not only track their own progress, but to also see how they compared to their fellow participants.

Building on the success of their experience with QuickSight and the Scavenger Hunt, we wanted to push the gamification and dashboards concept further so Chief Information and Security Officers (CISOs) and security teams could identify and mitigate the human side of ransomware risk. We developed Snack Attack!, a gamified learning experience that shows an organization how employees are performing in six key defensive areas where ransomware can be prevented. In 2021, over 80% of cyber breaches involved human error of some kind. Employees must have a fundamental awareness of cybersecurity and the ability to apply cyber knowledge within the scope of their jobs. Snack Attack! and QuickSight proved to be a great product to visualize and action on areas of human risk and sentiment for senior leadership.

A screenshot of a Snack Attack! dashboard

With Snack Attack!, we looked at Cybersecurity Awareness Month from the viewpoint of the awareness practitioner. The program itself focuses on driving engagement through an entertaining storyline with creative visuals. We chose to use the data from the training to help our customers build their awareness programs going forward. The dashboards included in Snack Attack! give the security awareness practitioner insights into the learned behavior of their users. Quick visualizations of learners’ scoring in Snack Attack! can act as an audit of the effectiveness of their existing program and provide a roadmap for future trainings.

Paving the way in using analytics for customer security

The SANS Institute brings together security awareness training programs with a metrics-based approach through out-of-the-box analytics dashboards so our customers can assess and manage human risk successfully. With QuickSight, we were able to rapidly innovate, developing valuable data products at a speed we could not have otherwise. Without up-front investments to get started and with the low cost to try with usage-based pricing, we were able to quickly ideate, build, and deploy customer-facing analytic products to drive security awareness within our customer organizations. Our analytics solutions differentiate us from existing enterprise products. With QuickSight, we are able to show organizations where they have cyber risk.

With the delivery of analytics solutions to customers, the SANS Institute is not only a top cybersecurity training, learning, and certification platform, but also a technology provider that helps customers use data and insights to make meaningful change in their organization. Moving forward, we have identified an expansion of QuickSight dashboards into our larger suite of assessments as the next logical step. Along with the Behavioral Risk Assessment, we offer Knowledge and Culture assessments to help security awareness practitioners better understand where and how to apply training and gauge the effectiveness of their programs. Because of the success we have had with QuickSight on our existing projects, we feel that similar dashboards can provide even more value to our customers.

To learn more about how QuickSight can help your business with dashboards, reports, and more, visit Amazon QuickSight.


About the Author

Carl R. Marrelli is the Director of Business Development and Digital Programs at SANS Institute. Based in Charlotte, NC, he has extensive experience in cross-functional team leadership, product management, and product marketing. Previously as Head of Product at SANS, Carl led the product management team for the Online Training and Security Awareness divisions through a significant growth period. Carl’s unique perspective and innovative ideas, support SANS as the company continues its mission to empower cybersecurity practitioners around the world.

Implementing up-to-date images with automated EC2 Image Builder pipelines

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/implementing-up-to-date-images-with-automated-ec2-image-builder-pipelines/

This blog post is written by Devin Gordon, Senior Solutions Architect, WWPS, and Brad Watson, Senior Solutions Architect, WWPS.

Amazon EC2 Image Builder is a service designed to simplify the creation and deployment of customized Virtual Machine (VM) and container images on AWS or on-premises. The posts Automate OS Image Build Pipelines with EC2 Image Builder and Quickly build STIG-compliant Amazon Machine Images using Amazon EC2 Image Builder show how you can create secure images using EC2 Image Builder pipelines.

In this post, we demonstrate how to automatically keep your base or standard images current, incorporating patches and any other changes using EC2 Image Builder pipelines. We also demonstrate how to keep workload-specific images current using Cascading Pipelines, a feature of EC2 Image Builder.

Dependency updates

You can use the Dependency update feature of EC2 Image Builder pipelines to automatically update your standard image based on changes to your build components.

When you create an EC2 Image Builder pipeline, you can choose to run the pipeline on a schedule, either using a schedule builder or a CRON expression (a method of defining minute, hour, day and month for scheduling). Furthermore, you can choose to only run the pipeline if a component in the pipeline or the source image has changed. This is referred to as a dependency update as shown in the following image.

Figure 1 An example EC2 Image Builder pipeline schedule with dependency update settings

Figure 1: An example EC2 Image Builder pipeline schedule with dependency update settings

When you select “Run pipeline at the scheduled time if there are dependency updates,” your pipeline only executes if the Base AMI or any Build or Test components have changed. The version of your components must be updated for this capability to work. Amazon-provided components include versioning out of the box. Here is an example of three versions of an Amazon-provided Build component that apply Security Technical Implementation Guide (STIG) baselines to Linux images.

Figure 2 Different versions of one Amazon-managed Build component

Figure 2: Different versions of one Amazon-managed Build component

When a new STIG baseline build component is released, the component’s version is incremented. If a pipeline includes this type of versioned Build component and utilizes the dependency updates capability, then the pipeline automatically runs at the next scheduled interval after the component is updated. Pipelines utilizing this capability will run when the base AMI changes or when a Build or Test component changes.

Notifications

To receive notifications about the pipeline execution, you can enable an Amazon Simple Notification Service (Amazon SNS) topic from within EC2 Image Builder. Under the Infrastructure Configuration section of the EC2 Image Builder pipeline, identify an SNS topic as shown in the following image.

Figure 3 An example SNS topic for sending pipeline execution notifications

Figure 3: An example SNS topic for sending pipeline execution notifications

The SNS topic receives a notification if a pipeline runs and completes with a status of AVAILABLE or FAILED. This occurs even when a pipeline execution is triggered by a component change that you didn’t directly initiate, such as when a new version of an Amazon-managed build component is released.

Even if no other aspects of the infrastructure configuration are used in the pipeline (instance type, security group, subnet, etc.), the SNS topic capability can be used to send a notification when the pipeline executes. With this in mind, you can leverage Amazon SNS to make sure that you’re always notified of any pipeline executions as well as trigger AWS Lambda functions for automation.

Cascading pipelines

Cascading Pipelines are a feature of EC2 Image Builder that you can use to create workload-specific images from a standard secured image (aka “gold image”) of an organization. The following image shows how you can use Cascading Pipelines to keep workload specific images updated.

Figure 4 An example workflow for a EC2 Image Builder Cascading Pipelines

Figure 4: An example workflow for a EC2 Image Builder Cascading Pipelines

You create a gold image pipeline for a hardened base operating system (OS) using the steps outlined in Automate OS Image Build Pipelines with EC2 Image Builder. This pipeline could include a base OS, OS patches, Build components to harden the OS (such as STIG or CIS baselines), as well as any additional software required by the organization (agents, etc.). Do not include application- or workload-specific software in the pipeline. Infrastructure or distribution components may not be included in the pipeline to maintain flexibility for using the gold image. For example, you typically wouldn’t want to include VPC configurations in your golden AMI build because that would constrain the AMI to a particular VPC.

To create a Cascading Pipeline that uses the gold image for applications or workloads, in the Base Image section of the EC2 Image Builder console, choose Select Managed Images.

Figure 5 Selecting the base image of a pipeline

Figure 5: Selecting the base image of a pipeline

Then, select “Images Owned by Me” and under Image Name, select the EC2 Image Builder pipeline used to create the gold image. Moreover, select “Use Latest Available OS Version” under Auto-versioning options to make sure that the Cascading Pipeline is executed any time there is a change to the base image.

Figure 6 Choosing the base golden image from a previous pipeline execution

Figure 6: Choosing the base golden image from a previous pipeline execution

Use this configuration to maintain images for each application or workload which utilizes the gold image. Any time that an update is made to the gold image, application pipelines execute, thus providing updated images. To send notifications, SNS topics are enabled on each workload-specific pipeline.

In this post, we demonstrated how to automatically update images for any changes using EC2 Image Builder pipelines. We also demonstrated how to keep workload specific images using Cascading Pipelines. Using these features, you can make sure that your organization stays up-to-date on the latest OS patches and dependency changes, without requiring human intervention. For more information on EC2 Image Builder, see the official documentation.

How Morningstar used tag-based access controls in AWS Lake Formation to manage permissions for an Amazon Redshift data warehouse

Post Syndicated from Don Drake original https://aws.amazon.com/blogs/big-data/how-morningstar-used-tag-based-access-controls-in-aws-lake-formation-to-manage-permissions-for-an-amazon-redshift-data-warehouse/

This post was co-written by Ashish Prabhu, Stephen Johnston, and Colin Ingarfield at Morningstar and Don Drake, at AWS.

With “Empowering Investor Success” as the core motto, Morningstar aims at providing our investors and advisors with the tools and information they need to make informed investment decisions.

In this post, Morningstar’s Data Lake Team Leads discuss how they utilized tag-based access control in their data lake with AWS Lake Formation and enabled similar controls in Amazon Redshift.

The business challenge

At Morningstar, we built a data lake solution that allows our consumers to easily ingest data, make it accessible via the AWS Glue Data Catalog, and grant access to consumers to query the data via Amazon Athena. In this solution, we were required to ensure that the consumers could only query the data to which they had explicit access. To enforce our access permissions, we chose Lake Formation tag-based access control (TBAC). TBAC helps us categorize the data into a simple, broad level or a complex, more granular level using tags and then grant consumers access to those tags based on what group of data they need. Tag-based entitlements allow us to have a flexible and manageable entitlements system that solves our complex entitlements scenarios.

However, our consumers pushed us for better query performance and enhanced analytical capabilities. We realized we needed a data warehouse to cater to all of these consumer requirements, so we evaluated Amazon Redshift. Amazon Redshift provides us with features that we could use to work with our consumers and enable their analytical requirements:

  • Better performance for consumers’ analytical requirements
  • Ability to tune query performance with user-specified sort keys and distribution keys
  • Ability to have different representations of the same data via views and materialized views
  • Consistent query performance regardless of concurrency

Many new Amazon Redshift features helped solve and scale our analytical query requirements, specifically Amazon Redshift Serverless and Amazon Redshift data sharing.

Because our Lake Formation-enforced data lake is a central data repository for all our data, it makes sense for us to flow the data permissions from the data lake into Amazon Redshift. We utilize AWS Identity and Access Management (IAM) authentication and want to centralize the governance of permissions based on IAM roles and groups. For each AWS Glue database and table, we have a corresponding Amazon Redshift schema and table. Our goal was to ensure customers who have access to AWS Glue tables via Lake Formation also have access to the corresponding tables in Amazon Redshift.

However, we faced a problem with user-based entitlements as we moved to Amazon Redshift.

The entitlements problem

Even though we added Amazon Redshift as part of our overall solution, the entitlement requirements and challenges that came with it remained the same for our users consuming via Lake Formation. At the same time, we had to find a way to implement entitlements in our Amazon Redshift data warehouse with the same set of tags that we had already defined in Lake Formation. Amazon Redshift supports resource-based entitlements but doesn’t support tag-based entitlements. The challenge we had to overcome was how to map our existing tag-based entitlements in Lake Formation to the resource-based entitlements in Amazon Redshift.

The data in the AWS Glue Data Catalog needed to be also loaded in the Amazon Redshift data warehouse native tables. This was necessary so that the users get a familiar list of schema and tables that they are accustomed to seeing in the Data Catalog when accessing via Athena. This way, our existing data lake consumers could easily transition to Amazon Redshift.

The following diagram illustrates the structure of the AWS Glue Data Catalog mapped 1:1 with the structure of our Amazon Redshift data warehouse.

Shows mapping of Glue databases and tables to Redshift schemas and tables.

We wanted to utilize the ontology of tags in Lake Formation to also be used on the datasets in Amazon Redshift so that consumers could be granted access to the same datasets in both places. This enabled us to have a single entitlement policy source API that would grant appropriate access to both our Amazon Redshift tables as well as the corresponding Lake Formation tables based on the Lake Formation tag-based policies.

Entitlement Policy Source is used by Lake Formation and Redshift

To solve this problem, we needed to build our own solution to convert the tag-based policies in Lake Formation into grants and revokes in the resource-based entitlements in Amazon Redshift.

Solution overview

To solve this mismatch, we wanted to synchronize our Lake Formation tag ontology and classifications to the Amazon Redshift permission model. To do this, we map Lake Formation tags and grants to Amazon Redshift grants with the following steps:

  1. Map all the resources (databases, schemas, tables, and more) in Lake Formation that are tagged to their equivalent Amazon Redshift tables.
  2. Translate each policy in Lake Formation on a tag expression to a set of Amazon Redshift table grants and revokes.

The net result is that when there is a tag or policy change in Lake Formation, a corresponding set of grants or revokes are made to the equivalent Amazon Redshift tables to keep our entitlements in sync.

Map all tagged resources in Lake Formation to Amazon Redshift equivalents

The tag-based access control of Lake Formation allowed us to apply multiple tags on a single resource (database and table) in the AWS Glue Data Catalog. If visualized in a mapping form, the resource tagging can be displayed as how multiple tags on a single table would be flattened into individual entitlements on Amazon Redshift tables.

Mapping of tags in Lake Formation to Redshift tables

Translate tags to Amazon Redshift grants and revokes

To enable the migration of the tag-based policy enforced in Lake Formation, the permissions can be converted into simple grants and revokes that can be done on a per-group level.

There are two fundamental parts to a tag policy: the principal_id and the tag expression (for example, “Acess Level” = “Public”). Assuming that we have an Amazon Redshift database group for each principal_id, then the resources that represent the tag expression can be permissioned accordingly. We plan on migrating from database groups to database roles in a future implementation.

mapping of tags to Redshift user group

The solution implementation

The implementation of this solution led us to develop two components:

  • The mapper service
  • The Amazon Redshift data configuration

The mapper service can be thought of as a translation service. As the name suggests, it has the core business logic to map the tag and policy information into resource-based grants and revokes in Amazon Redshift. It needs to mimic the behavior of Lake Formation when handling the tag policy translation.

To do this translation, the mapper needs to understand and store the metadata at two levels:

  • Understanding what resource in Amazon Redshift is to be tagged with what value
  • Tracking the grants and revokes already performed so they can be updated with changes in the policy

To do this, we created a config schema in our Amazon Redshift cluster, which currently stores all the configurations.

As part of our implementation, we store the mapped (translated) information in Amazon Redshift. This allows us to incrementally update table grants as Lake Formation tags or policies changed. The following diagram illustrates this schema.

schema of configuration stored in Redshift

Business impact and value

The solution we put together has created key business impacts and values out of the current implementation and allows us greater flexibility in the future.

It allows us to get the data to our users faster with the tag policies applied in Lake Formation and translated directly to permissions in Amazon Redshift with immediate effect. It also allows us to have consistency in permissions applied in both Lake Formation and Amazon Redshift, based on the effective permissions derived from tag policies. And all this happens via a single source that grants and revokes permissions across the board, instead of managing them separately.

If we translate this into the business impact and business value that we generate, the solution improves the time to market of our data, but at the same time provides consistent entitlements across the business-driven categories that we define as tags.

The solution also opens up solutions to add more impact as our product scales both horizontally and vertically. There are potential solutions we could implement in terms of automation, users self-servicing their permissions, auditing, dashboards, and more. As our business scales, we expect to take advantage of these capabilities.

Conclusion

In this post, we shared how Morningstar utilized tag-based access control in our data lake with Lake Formation and enabled similar controls in Amazon Redshift. We developed two components that handle mapping of the tag-based access controls to Amazon Redshift permissions. This solution has improved the time to market for our data and provides consistent entitlements across different business-driven categories.

If you have any questions or comments, please leave them in the comments section.


About the Authors

Ashish Prabhu is a Senior Manager of Software Engineering in Morningstar, Inc. He focuses on the solutioning and delivering the different aspects of Data Lake and Data Warehouse for Morningstar’s Enterprise Data and Platform Team. In his spare time he enjoys playing basketball, painting and spending time with his family.
Stephen Johnston is a Distinguished Software Architect at Morningstar, Inc. His focus is on data lake and data warehousing technologies for Morningstar’s Enterprise Data Platform team.

Colin Ingarfield is a Lead Software Engineer at Morningstar, Inc. Based in Austin, Colin focuses on access control and data entitlements on Morningstar’s growing Data Lake platform.

Don Drake is a Senior Analytics Specialist Solutions Architect at AWS. Based in Chicago, Don helps Financial Services customers migrate workloads to AWS.
Showpad accelerates data maturity to unlock innovation using Amazon QuickSight

Post Syndicated from Shruthi Panicker original https://aws.amazon.com/blogs/big-data/showpad-accelerates-data-maturity-to-unlock-innovation-using-amazon-quicksight/

Showpad aligns sales and marketing teams around impactful content and powerful training, helping sellers engage with buyers and generate the insights needed to continuously improve conversion rates. In 2021, Showpad set forth the vision to use the power of data to unlock innovations and drive business decisions across its organization. Showpad’s legacy solution was fragmented and expensive, with different tools providing conflicting insights and lengthening time to insight. The company decided to use AWS to unify its business intelligence (BI) and reporting strategy for both internal organization-wide use cases and in-product embedded analytics targeted at its customers.

Showpad built new customer-facing embedded dashboards within Showpad eOSTM and migrated its legacy dashboards to Amazon QuickSight, a unified BI service providing modern interactive dashboards, natural language querying, paginated reports, machine learning (ML) insights, and embedded analytics at scale.

In this post, we share how Showpad used QuickSight to streamline data and insights access across teams and customers. Showpad migrated over 70 dashboards with over 1,000 visuals. They have rolled out the solution to all its 600 employees, increased dashboard development activity by three times, and reduced dashboard turnaround time from months to weeks. Showpad also launched dashboards and reports to over 1,300 customers worldwide, providing access to tens of thousands of users across all its customers.

Streamlining data-driven decisions by defragmenting the data and reporting architecture

Founded in 2011, dual headquartered in Belgium and Chicago and with offices around the world, Showpad provides a single destination for sales representatives to access all sales content and information, along with coaching and training tools to create informed, upskilled, and trusted buying teams. The platform also provides analytics and insights to support successful information sharing and fuel continuous improvement. In 2021, Showpad decided to take the next step in its data evolution and set forth the vision to power innovation, product decisions, and customer engagement using data-driven insights. This required Showpad to accelerate its data maturity as a company by mindfully using data and technology holistically to help its customers.

But the company’s legacy BI solution and data were fragmented across multiple tools, some with proprietary logic. “Each of these tools were getting data from a different place, and that’s where it gets difficult,” says Jeroen Minnaert, head of data at Showpad. “If each tool tells a different story because it has different data, we won’t have alignment within the business on what this data means.” Showpad also struggled with data quality issues in terms of consistency, ownership, and insufficient data access across its targeted user base due to a complex BI access process, licensing challenges, and insufficient education.

Showpad wanted to unify all the data into a single unified interface through a data lake, democratize that data through a BI solution such that autonomous teams across the company could effectively use data, and drive and unlock innovation in the company through advanced insights data, artificial intelligence, and ML. The company already used AWS in other aspects of its business and found that QuickSight would not only meet all its BI and reporting needs with seamless integrations into the AWS stack, but also bring with it several unique benefits unlike incumbents and other tools evaluated. “We chose QuickSight because of its embedded analytic capabilities, serverless architecture, and consumption-based pricing,” says Minnaert. “Using QuickSight to launch interactive dashboards and reporting for our customers, along with the ability for our customer success teams to create or alter dashboard prototypes on our internal-facing QuickSight instance and then promote those dashboards to customers through the product, was a very compelling use case.”

QuickSight would help local data stewards, who weren’t technical but knew the use cases intimately, to create their own dashboards and prototype them with their customers before promoting them through the product. “The serverless model was also compelling because we did not have to pay for server instances nor license fees per reader. With QuickSight, we pay for usage. This makes it easy for us to provide access to everyone by default. This is a key pillar in our ability to democratize data,” says Minnaert.

A screenshot of Showpad's Platform/Adoption dashboard

Architecting a portable data layer and migrating to QuickSight to accelerate time to value

After choosing QuickSight as its solution in November 2021, Showpad took on two streams of development: migrating internal organization-wide BI reporting and building in-product reporting using embedded analytics. Showpad worked closely alongside the QuickSight team to have a smooth rollout. The company involved members of the QuickSight team in its internal communications and set up meetings every 2 weeks to resolve difficult issues quickly.

On the internal reporting front, the data team took a “working backwards” approach to make sure it had the right approach before going all in with all existing dashboards. Showpad selected five difficult and complex dashboards and took 3 months to explore various possibilities using QuickSight. For example, the team determined that user log-in would be automated with single sign-on and Okta and built a plan for assets organization, asset promotion, and access controls. The company also used the opportunity to reimagine its data pipeline and architecture. A key architectural decision that Showpad took during this time was to create a portable data layer by decoupling the data transformation from visualization, ML, or ad hoc querying tools and centralizing its business logic. The portable data layer facilitated the creation of data products for varied use cases, made available within various tools based on the need of the consumer—be it a business analyst, data scientist, or business user.

After the solution approach was decided on and the foundation was built, the team wanted to scale. However, with 70 dashboards with over 1,000 visuals with varying levels of complexities, including proprietary logic unique to certain tools, and data from over 1,000 tables ingesting data from over 20 data sources, the team decided to take a measured approach to the migration. The entire data team of 20 people were “all on hands on deck” for the project.

First, Showpad created a landscape of all the dashboards, connecting data sources and dependencies before prioritizing the migration order. The company decided to start with dashboards with the fewest dependencies, like product and engineering dashboards that had a single data source, followed by revenue operations dashboards with a couple of data sources, and lastly with customer success and marketing dashboards that combined product and engineering and revenue operations data. After migration was complete, Showpad validated all the numbers and worked with business stakeholders for quality assurance. It launched the first set of dashboards in April 2022, followed by customer success and marketing dashboards in July 2022. As of January 2023, Showpad’s QuickSight instance includes over 2,433 datasets and 199 dashboards.

Showpad also achieves benefits for its customers by using QuickSight to deliver a wide variety of insights, including usage dashboards, industry comparisons, user comparison, group comparison, and revenue attribution. On the second workstream of in-product customer-facing reporting, Showpad released its first version of QuickSight reporting to customers in June 2022. “We went through user research, development, and beta tests in a span of 6 months, which was a fast turnaround and a big win for us,” says Minnaert. And Showpad aims to further accelerate the turnaround time to make a report and ship it to a customer.

With the foundational architecture now in place, shipping to a customer can happen in a few sprints, with most of the time spent on iterating and fine-tuning insights instead of engineering a scalable reporting solution. Showpad can also improve the insights it offers to customers. “Using QuickSight in our product makes it a powerful tool,” says Minnaert. “We can launch reporting for our customers so that they can look at and interpret data by themselves.” Showpad can then follow up with tailor-made reporting for each customer using the same data so that it tells a consistent story.

After a dashboard is agreed on, the dashboard can go through Showpad’s automated dashboard promotion process that can take an idea from development to production to a smile on a customer’s face in weeks, not months.

A screenshot of their Shared Space engagement dashboard

Unlocking innovation with self-service BI and rapid prototyping

By providing dashboard and report building to analysts and nontechnical users, Showpad drastically reduced overall turnaround time to build and deliver insights, down from months to weeks. Showpad also increased dashboard development activity by three times across the organization.

Showpad users can quickly prototype reports in a well-known environment—building reports using QuickSight, and then testing them with customers by helping customers understand how the reporting would look and function. “After we settle on reports or dashboards, it does not take much engineering effort to bring them to production,” says Minnaert. “We can make a lot of innovation happen by quickly prototyping and bringing validated prototypes to production.” Showpad’s users and customers also benefit from performance gains with 10 times increased speed when using SPICE (Super-fast, Parallel, In-memory Calculation Engine), which is the robust in-memory engine that QuickSight uses. It takes only seconds to load dashboards.

Because QuickSight is serverless and uses a session-based pricing model, Showpad expects to see cost savings. By paying per use, Showpad can easily provide access to all its users and customers without purchasing expensive per-reader licenses. Showpad also doesn’t need to pay for server instances or maintain infrastructure for BI. In addition, Showpad can deprecate custom reporting, infrastructure, and multiple tools with the new data architecture and QuickSight. “Much of our cost savings will come from being able to deprecate the custom reporting that we’ve made in the past,” says Minnaert. “The custom reporting used a lot of infrastructure that we no longer need to maintain.” Showpad expects to see a three times increase in projected return on investment in the upcoming year.

Showpad completed its internal BI migration to QuickSight by the end of 2022. Showpad also continues to expand the in-product reporting while continuing to optimize performance for the best customer experience. Showpad hopes to further reduce the time it takes to load a dashboard to under 1 second.

In conjunction with Showpad’s new portable data layer, QuickSight helps users of all types across its organization and customers self-serve data and insights rapidly. Everyone in Showpad gets access to data and insights the day they onboard with Showpad. To make self-service even easier, Showpad will soon launch embedded Amazon QuickSight Q so anyone can ask questions in natural language and receive accurate answers with relevant visualizations that help them gain insights from the data. By helping business users and experts rapidly prototype dashboards and reports in line with user and customer needs, Showpad uses the power of data to unlock innovation and drive growth across its organization. “QuickSight has become our go-to tool for any BI requirement at Showpad—both internal and external customer facing, especially when it comes to correlating data across departments and business units,” says Minnaert.

Get started with QuickSight

Migrating to QuickSight enabled Showpad to streamline data and insights access across teams and customers and reduced overall turnaround time to build and deliver insights from months to weeks.

Learn more about unleashing your organization’s ability to accelerate revenue growth with Showpad. To learn more about how QuickSight can help your business with dashboards, reports, and more, visit Amazon QuickSight.


About the Author

Shruthi Panicker is a Senior Product Marketing Manager with Amazon QuickSight at AWS. As an engineer turned product marketer, Shruthi has spent over 15 years in the technology industry in various roles from software engineering, to solution architecting to product marketing. She is passionate about working at the intersection of technology and business to tell great product stories that help drive customer value.

Software-defined edge architecture for connected vehicles

Post Syndicated from James Simon original https://aws.amazon.com/blogs/architecture/software-defined-edge-architecture-for-connected-vehicles/

To remain competitive in a marketplace that increasingly views transportation as a service emphasizing customer experience, vehicle capabilities and mobility applications need to improve and increase value over time, much like the internet of things and smart phones have done.

Vehicle manufacturers and fleet operators are responding to this change by using data to inform and operate their businesses, and by adopting software-defined vehicle features and capabilities. In the broader transportation community, insurance providers are evolving to usage-based insurance, which offers rates that are based on a customer’s risk profile rather than a general population. Telematics service providers are expanding their offerings to fleet operators to include machine learning (ML)-driven capabilities like driver coaching, compliance, and predictive maintenance. Rental car providers are developing apps that provide a personalized in-vehicle experience.

All of these features rely on in-vehicle data collection and processing, evolving vehicles from simple data gathering sensors to fully smart devices. To meet these demands, you can adopt cloud native architectures that use microservices, containers, and declarative application programming interfaces (APIs). This blog post explores a system architecture AWS and Luxsoft have developed together in order to help our customers reduce friction and accelerate time to market for the development, deployment and operation of edge applications required to make vehicles into smart devices.

Software-defined edge

Software is becoming more critical to vehicle function. A modern car has approximately 70-100 Electronic Control Units (ECUs), which control most core functions in the engine, transmission, Heating, ventilation, and air conditioning (HVAC) Automatic Brake System (ABS), body, and airbag hardware components. With new features such as infotainment systems, autonomous driving (AD), and advanced driver assistance systems (ADAS), modern cars use approximately 100 million lines of code, and this is increasing rapidly. ECU and software complexity produce challenges with portability of applications, this could be due to variations of the hardware, or CAN and other network communication differences, without an abstraction layer, application software must be conformed to the operating environment.

One difficulty presented by this increasing complexity and the multitude of integration points and communication interfaces at the edge is that applications typically must be re-developed, customized or at least cross-compiled to fit each hardware platform, often requiring a lengthy integration development and testing cycle for each new device. As a result, edge applications executing ML and other data-driven workloads can produce a pace that is slower than consumer expectations.

The development pace for software-defined vehicles (SDVs) relies on reusing and redeploying software applications. Software reuse is a challenge when target hardware and processing environments aren’t designed in a common way. Therefore, an early step in developing SDVs is to address these challenges at the vehicle edge, that is to say, the externally connected vehicle devices.

System architecture

To help address the challenges of creating reusable software and applications for the vehicle edge, we worked with AWS Partner DXC Luxsoft to create an end-to-end system architecture. The architecture in Figure 1 uses software-defined mobility devices at the vehicle edge to connect to multiple hardware components.

AWS Partner DXC Luxsoft to create an end-to-end system architecture

Figure 1. AWS Partner DXC Luxsoft to create an end-to-end system architecture

Let’s explore this architecture step by step.

  1. Edge application Developers check in source code to a CI/CD system for build and test. Applications are built as containers and tested on Amazon EC2 Elastic Compute Cloud (Amazon EC2) instances with target same Amazon Machine Images (AMI).
  2. Edge application containers are stored in Amazon Elastic Container Registry (Amazon ECR).
  3. Containers are registered as AWS IoT Greengrass components for target devices.
  4. Deploy edge applications to multiple target types using AWS IoT Greengrass.
  5. Data is published back to AWS through AWS IoT Core basic telemetry or AWS IoT Fleetwise.
  6. AWS IoT Core routes data to connected vehicle databases and services for further processing. Alternatively, AWS IoT Fleetwise-collected data is routed through AWS IoT Fleetwise.
  7. The Fleet Management portal allows fleet managers to view results produced by applications and services and data collected by AWS IoT Fleetwise. This can include geolocation, vehicle health, Usage Based Insurance (UBI), or other driver scores.
  8. Mobile clients can be created to allow end users and consumers to view application and service results and scores for applications like UBI.

How it works

This technology stack abstracts the specific hardware used, presenting a common run environment that you can deploy to devices that are based on ARM processors with ARM Sytem Ready firmware, including Amazon EC2 Graviton instances.

This architecture uses the following:

  • Device software stack with an ARM System Ready board support package
  • Yocto custom Linux build with the SOAFEE EWAOL layer(s) and AWS IoT Greengrass
  • Instance of the AWS IoT Fleetwise edge agent
  • Application containers for pre and post processing of data collected by AWS IoT Fleetwise or other applications

We paired this stack with AWS IoT Greengrass V2 and a container-based version of AWS IoT Fleetwise edge agent that we been modified to publish to a local broker first to allow pre and post-processing. This also makes AWS IoT Fleetwise-collected data available to other application containers running on the device. The pre- and post-processing containers prepare messages and data for use by other edge applications or exchange with the cloud services and will be available with the architecture source code.

Benefits

Because this architecture is container-based and abstracts the hardware, deploying and updating applications becomes more efficient. Because Amazon EC2 Graviton instances are ARM-based, you can deploy specific AMIs and configurations that contain this architecture’s technology stack as part of a continuous integration and continuous deployment (CI/CD) pipeline. This means that you can develop new applications and services entirely in the cloud, test them in the cloud with bit equivalent binaries and containers, and then deploy them to hardware components. This can save weeks to months of development and verification through the use of automation. The use of ARM based systems cloud native development and testing strategies can be applied, reducing the need for hardware test equipment and bringing new revenue streams and customer experiences to market at a pace that matches the current demand.

Conclusion

With this architecture, you can develop and deliver new edge processing applications to one or more vehicle device platforms. You can also develop, test, and deploy purpose-built edge compute applications as containerized AWS IoT Greengrass V2 components, including applications like Usage Based Insurance, over the air update agents, and driver distraction.

With this architecture alone in place, value can quickly be added by developing AWS IoT Fleetwise data campaigns targeting specific data required to fulfill business value for consumers, operators or fleet managers, such as vehicle battery state of charge or health indicators.

You can add value to this architecture by developing AWS IoT Fleetwise data campaigns for specific data required to fulfill business value for consumers, operators, or fleet managers. Examples of this data include vehicle battery state of charge and health indicators.

If you’re interested in creating or contributing to a common architecture that can accelerate developing and deploying edge applications to multiple hardware components, contact Connected Vehicle Tech Strategy Lead James Simon or AWS Partner DXC Luxsoft for a working demonstration or to start a proof of concept.

Extending CloudFormation and CDK with Third-Party Extensions

Post Syndicated from Lucas Chen original https://aws.amazon.com/blogs/devops/extending-cloudformation-and-cdk-with-third-party-extensions/

Did you know you can use CloudFormation to manage third-party resources? The AWS CloudFormation Public Registry provides a searchable collection of CloudFormation extensions and makes it easy to discover and provision them in CloudFormation templates and AWS Cloud Development Kit (CDK) applications. In the past three months, we’ve added a number of new, exciting partners to the Public Registry, including GitLab, Okta, and PagerDuty.

The extensions available on the registry are wide-ranging and include third-party resources from partners such as MongoDB; hooks, which are preventative controls that add safeguards to provisioning; and modules, which are re-usable components that take into account best practices and opinionated definitions of resources. AWS Partner Network (APN), third parties, and the developer community contribute these extensions to the Public Registry. Using extensions, customers no longer need to create and maintain custom provisioning logic for resource types from third-party vendors.

Over last few months, AWS collaborated with partners to develop and publish over 80 new resources across 14 providers to Public Registry for CloudFormation. Below is a summary of the new resource type additions.

Recently Updated Third-Party Providers

Provider Use case
MongoDB Atlas

Manage components in MongoDB Atlas. Add, edit, or delete administrative objects within Atlas, including projects, users, and database deployments

Note: You cannot read or write data to Atlas Clusters with Atlas Admin APIs and AWS CloudFormation resources. To read and write data in Atlas, you must use the Atlas Data API

GitLab Manage the users and groups in an organization, set up a new project with the right users, groups, and access token, tag a project automatically for every active CI/CD deployment
New Relic Create a new Dashboard with custom Pages, Widgets and Layout, add tags to your data to help improve data organization and findability, workloads-related tasks
GitHub Manage the users and groups in an organization, set up a new project with the right users, groups, and access token, Add a webhook to a repo
Dynatrace Set up a new project with service level objective, locations, monitors and metrics
Okta Onboard a new application into Okta with the right users and groups
PagerDuty Set up monitoring of a new or existing application
Databricks Set up a Databricks cluster and jobs
Fastly Configure Fastly as a CDN for your web app
BigID Connect S3 and DynamoDB data sources into your BigID application
Rollbar Set up a new Rollbar project and manage rules, teams, and users
Cloudflare Configure a DNS record and load-balancing using Cloudflare
Lacework Configure Lacework alert profiles, rules, channels and manage queries
Snowflake Create databases, users, and manage privileges

Key Benefits

Here are some of the benefits for extension builders and consumers when publishing extensions to the public registry:

  1. Discoverability – Publishing your extensions in the public registry will make them discoverable by 1M+ active CloudFormation and CDK customers.
  2. CDK Support – We’re seeing rapid growth in the adoption of the CDK amongst the developer population. Upon publishing to the registry, L1 CDK Constructs will automatically be created for your third party resources making them compatible with the CDK with no added work required. These constructs will also be listed on Construct Hub and aids discoverability discoverable by customers. Note: Automated L1 CDK construct generation is currently an experimental feature.
  3. Drift detection – Third-party resource types in the public registry also integrate with drift detection. After creating a resource from a third-party resource type, CloudFormation will detect changes to the third-party resource from its template configuration, known as configuration drift, just as it would with AWS resources.
  4. AWS Config – You can also use AWS Config to manage compliance for third-party resources consumed from the registry. The resource types are automatically tracked as Configuration Items when you have configured AWS Config to record them, and used CloudFormation to create, update, and delete them. Whether the resource types you use are third-party or AWS resources, you can view configuration history for them, in addition to being able to write AWS Config rules to verify configuration best practices.
  5. Abstraction of Best Practices with Modules – Browse and use modules from the registry when creating your CloudFormation templates to ensure you’re provisioning resources while adhering to best practices.
  6. AWS Cloud Control API – The AWS Cloud Control API allows AWS partners and customers to interface with your resource type through API calls using Create, Read, Update, Delete, and List (CRUD-L) operations. Resources in the registry will be automatically integrated with our AWS Cloud Control API and expands your third party resource compatibility to even more AWS services and IaC tools.

We’ve seen great momentum from our partners and developer community over the past year. We are looking forward to continued investment and innovation in the Public Registry.

How to Get Started

For Resource Type Users: Explore and Activate Third Party Resource Types

Third party resource types must first be activated before they can be used. You do this by logging into your AWS Console > Navigate to CloudFormation > Registry > Public extensions > Set the Publisher to Third Party. This will show you a list of available third-party resources in your region (note that different regions may have a different set of third-party resource types). Select the radio box next to the resource types you want to activate and click the activate button at the top of the list.

Figure 1:

Don’t see the extension you need in the registry?

You can submit requests for new third-party extensions through our Community Registry Extensions Github repo issue tracker! Click the New Issue button and describe the third-party extension along with information about your use case.

For Developers and Publishers: Join the CloudFormation Developer Community and Start Building

You can see several of the community-built registry extensions in the AWS CloudFormation Community Registry Extensions repository and even contribute yourself. You can also read about the experiences and lessons learned from publishing to the Registry through this blog written by Cloudsoft.

For developers looking to create new resource types to add to the public Registry, follow this creating resource types walkthrough help you get started. If you need assistance creating, publishing resources, or just want to join the discussion, you can join the conversation today in our CloudFormation Discord Channel. We’d love to hear about your experiences and use cases in developing innovations with registry extensions.

About the authors:

Anuj Sharma

Anuj Sharma is a Sr Container Partner Solution Architect with Amazon Web Services. He works with ISV partners and drives Partner-AWS product development and integrations.

Lucas Chen

Lucas is a Senior Product Manager at Amazon Web Services. He leads the CloudFormation Registry and its integrations with third-party products. Prior to AWS, he spent 9 years at VMware working on its end user computing product, Workspace ONE.

Rahul Sharma

Rahul is a Senior Product Manager-Technical at Amazon Web Services with over two years of product management spanning AWS CloudFormation and AWS Cloud Control API.

Customize marketing messages and promotions for personalized outreach

Post Syndicated from binpazho original https://aws.amazon.com/blogs/messaging-and-targeting/customize-marketing-messages-and-promotions-for-personalized-outreach/

Introduction

Amazon Pinpoint is widely used by many customers for their various user engagement use cases like marketing campaigns, scheduled communications (newsletters, reminders, etc.), and transactional messaging. By using the message template feature in Amazon Pinpoint, customers can design messages personalized to the specific end users, by using variable attributes. While Amazon Pinpoint enables customers to include up to 250 attributes for each user, often times there might be need to pick and choose from a wide range of attributes about a user, that can lead to needing more than the allowed number of attributes.

The CampaignHook feature of Amazon Pinpoint can come to rescue for a situation like this. Using the CampainHook feature, we can filter out attributes that are not applicable to a specific user, while allowing to add new attributes, right before of sending the message. In this blog, I will walk you through how I have implemented the CampaignHook feature for a similar use case.

Sample Use-Cases

When setting up your Pinpoint campaign, following are the use cases where a CampaignHook can be enabled:

  • Retrieving data and perform custom compute logic in real time from third party data stores.
  • Filter endpoints out of the send: This is useful if you need to do some type of custom logic that you can’t do in Segmentation (custom opt-out, quiet time, campaign prioritization, etc.)
  • Avoid costly and time consuming Extract, Transform & Load (ETL) processes by accessing the data sources directly and applying custom compute logic in real-time.

Solution overview

CampaignHook Demo Architecture

The diagram above shows the solution that we will setup in this blog. As you can see, the Campaign event will trigger the Amazon Pinpoint Campaign. The event can be triggered from your web or mobile app that are accessed by your end-users, and can be setup to be triggered when the user performs a certain action. You can read more about setting up Amazon Pinpoint campaign in the user guide. By having the CampaignHook enabled on your Amazon Pinpoint campaign, the Lambda function that is configured with the CampaignHook will be triggered. This function will have access to the endpoint attributes passed by the Campaign event, and perform additional logic to derive new attributes for the user. Once all the new fields are derived, the function will update the user endpoint. Amazon pinpoint will then perform the next steps in the Campaign, and substitute the variables in the message template, before the personalized message is sent to the end user.

Prerequisites

  • AWS Account with Console and Programmatic access
  • Access to AWS CloudShell
  • Email channel enabled in Amazon Pinpoint

Building the demo

Build the Amazon Pinpoint Project

From the AWS Management console, go to Amazon Pinpoint and create a new project called “PinpointCampaignHookDemo”, and choose the option to enable the email channel. For more information about creating a project see the user guide, and follow the instructions here to setup your email channel.

If your account is in the Sandbox account, you will need to verify the email address, before you can send the email. You can follow the steps here to upgrade your account to a Production status if you are ready to deploy this solution to production.

Create the segment.

A segment is a group of your users that share certain attributes. For example, a segment might contain all of your users who use version 2.0 of your app on an Android device, or all users who live in the city of Los Angeles. You can send multiple campaigns to a single segment, and you can send a single campaign to multiple segments.

For this demo, let’s create a Dynamic Segment. Let’s call it ‘CampaignHookDemoSegment’.  Follow the steps here to create your Dynamic Segment.

Create a Segment

Setup message template

Let’s create our first template and call it “CampaignHookDemoTemplate”. You can read more about Amazon Pinpoint templates in the user guide.

For this demo, I have used the HTML template shown below, and I have 3 endpoint attribute variables: 2 that are passed from the campaign event trigger, and the third one (Company) that will be generated by the CampaignHook lambda function. For the subject of the email, I used “Campaign Hook Demo Campaign“.

Create eMail Template

The email template can be found in this GitHub repository.

Create Campaign

Next, create your campaign and use the Segment and email Template that you created in the previous steps by following the instructions here.

Select the ‘when an event occurs’ option to trigger the campaign when an event occurs. (This option will trigger the campaign when a specific event occurs). Yoy may also schedule your campaign to run on a scheduled bases as available in the setup screen. I used ‘CampaignHookTrigger’ as my event name.

Create a campaign

Set your Campaign Start date, time and end date. I have left all the other settings to default and saved the campaign. Now that you have successfully created your first Campaign, you are ready for the next steps.

Set Campaign Start and End Times

Create the Lambda function

This is the function that we will configure to trigger the Amazon pinpoint campaign event . From the Lambda console page, create a new function by clicking on the ‘Create function’ button. You can then pick the following options and create the function.

Name: Campaign_event_trigger_function

Runtime: Python 3.9 or higher.

Replace the default script with the code from the GitHub repository, and then deploy your code by clicking on the “Deploy” button.

Assign permissions

In-order for the Lambda function trigger to trigger the Pinpoint Campaign, you will need to add an inline policy to the IAM role that is attached to your Lambda function, by selecting Pinpoint as the service and PutEvents from the Write options. You can select the Lambda function as the resource to which the access will be granted.

{

    "Version" :"2012-10-17",

    "Statement":[

        {

            "Sid": "VisualEditor0",

            "Effect": "Allow",

            "Action": [

                "mobiletargeting:PutEvents"

            ],

            "Resource":"ARN of your Lambda function goes here."

        }

    ]

}

Create the CampaignHook Lambda function

This is the function that we will triggered from the CampaignHook. From your Lambda console, click on “Create function” and enter the basic information as shown below to create your function.

Name: CampaignHookFunction

Runtime: Python 3.9 or higher.

Next replace your default code with the sample GitHub code, and then deploy your code by clicking on the “Deploy” button.

Assign permissions

Next add permissions for Amazon Pinpoint to invoke the Lambda function by running the command below from your Command Shell. Replace the Lambda function name and Account number with yours.

aws lambda add-permission \

--function-name [YourCampaignHookLambdaFunctionName] \

--statement-id my-hook-id1 \

--action lambda:InvokeFunction \

--principal pinpoint.us-east-1.amazonaws.com \

--source-arn 'arn:aws:mobiletargeting:us-east-1:[YourAccountNumber]:apps/*'

You can also do this from the Lambda console, by clicking on “Configuration” and then scrolling down to “Resource based Policy” and by clicking on “Add permissions“.

Update Campaign settings to add the Campaign Hook

Now that you have the Lambda function that needs to act as the hook is created, and granted Amazon Pinpoint service to invoke that function, run the command below to update the Campaign settings to add the Campaign Hook. You can also set a default CampaignHook for ALL campaigns in the project by setting the CampaignHook property on the Project Settings via this API.

Replace the application-id (project id), campaign-id, and the arn of the Campaign Hook lambda function and run the command below. (You can find the Project ID by clicking on All Projects at the top-left of the Pinpoint Console. The Campaign ID can be found by opening your Pinpoint Project and then clicking Campaigns in the Pinpoint Console.)

aws pinpoint   update-campaign --application-id /

[your-application-id-goes-here] –campaign-id /

[your-campaign-id-goes-here] --cli-input-json '{"ApplicationId": /

"","CampaignId": "","WriteCampaignRequest": {"Hook": {"LambdaFunctionName": /

"your-CampaignHook-Function-goes-here","Mode": "FILTER","WebUrl": ""}}}'

You can optionally run the command below to make sure that the campaign settings have been updated:

aws pinpoint get-campaign –application-id [your-application-id-goes-here]  –campaign-id [your-campaign-id-goes-here]

Test your Campaign.

Go back to your Lambda function that you have created to trigger the Campaign in the “Create the Lambda function” step above. I have used the test event as shown below. Update the Application id to reflect your Project id and change the email address to the email you verified earlier and click on “Test” button.

{

    "application_id": "your application id",

    "endpoint_id": "223",

    "event_type": "CampaignHookEvent",

    "nextTestDate": "12/15/2025",

    "FirstName": "Jack",

    "email": "[email protected]",

    "userid": "Jack123"

}

You should now receive an email with the variables replaced with the values that was passed from your json payload. Further you can see the Company name was added to the endpoint from the CampaignHook Lambda, which is passed to the email template. If you have not received the email, please check the following:

  • The Lambda function ran without any errors
  • The LambdaHook function has the proper rights assigned to be invoked from Pinpoint
  • The From and To email id that you have used are verified in SES.

Verify email identity

Clean up resources

Once you are satisfied with your setup and testing, you can now clean up the resources by following the steps below:

  • Delete your Amazon Pinpoint Project, Campaign and Segment.
    • aws pinpoint delete-campaign –application-id [your appl id] –campaign-id [your campaign id]
    • aws pinpoint delete-segment –application-id [your app id]  –segment-id [your segment id]
    • aws pinpoint delete-app –application-id [your app id]
  • Delete you Lambda functions
    • aws lambda delete-function –function-name CampaignHookFunction
    • aws lambda delete-function –function-name Campaign_event_Trigger_Function

Conclusion

By dynamically generating the attributes in real-time, customers can now add greater levels of personalization within a single user message template. By invoking a Lambda function, you can perform custom compute logic, calculate new attribute values, and access external data stores, to modify the campaign’s segment, right before Amazon Pinpoint sends the message. Campaign Hook feature makes this possible as explained in this blog by running few basic CLI commands to enable the feature on your Amazon Pinpoint Campaign. You can read more about Amazon Pinpoint Campaign from the user guide documentation”.

How French Broadcaster TF1 Used AWS Cloud Technology and Expertise to Bring the FIFA World Cup to Millions

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/how-french-broadcaster-tf1-used-aws-cloud-technology-and-expertise-to-bring-the-fifa-world-cup-to-millions/

Three years before millions of viewers saw, arguably, one of the most thrilling World Cup Finals ever broadcast, TF1, the leading private TV channel in France, started a project to redefine the foundations of its broadcasting platform, including adopting a new cloud-based architecture.

They, and all other broadcasters, have been observing diminishing audiences for traditional over-the-air broadcasting and increasing popularity of digital platforms, such as smart TVs, and boxes like FireTV, ChromeCast, and AppleTV, as well as laptops, tablets, and mobile phones. According to Thierry Bonhomme, CTO of eTF1 (the group within TF1 in charge of digital platforms) whom I recently interviewed for the AWS French Podcast, digital broadcasting now accounts for 20–25 percent of TF1’s total audience.

Image of a soccer ball in a large stadium This online and mobile usage drives very specific traffic patterns on IT systems: a huge peak of connections and authentications in the few minutes before the start of a game and millions of video streams that must be delivered reliably over a variety of changing network qualities. In addition to these technical challenges, there is also an economic challenge: to deliver advertisements at key moments, such as before a national anthem or during a 15-minute half-time. The digital platform sells its own set of commercials, which are different from the commercials broadcast over the air, and might also be different from region to region. All these video streams have to be delivered to millions of viewers on a wide range of devices and a variety of network conditions: from 1 Gbs fiber at home down to 3 G networks in remote areas.

TF1’s approach to readiness included redesigning its digital architecture, setting up metrics showing how the new system is performing, and defining processes, roles and responsibilities for people in the team. As part of this preparation, AWS helped TF1 prepare their system to meet their scalability, performance, and security requirements.

In my conversation with Thierry, he described the two main objectives the company had when designing its new technical architecture for the future of broadcasting: first, the scalability of the platform and second, meet the demand for performance. Scalability is key to absorbing the peaks of concurrent viewers. And performance is required to ensure that the video streams start quickly (in less than 3 seconds) and there is no interruption of the video player (known as re-buffering). After all, nobody wants to know their team just scored by hearing their neighbors yelling before seeing it happen on the screen they’re watching.

The Technology
Starting in 2019, TF1 started to redesign its digital broadcasting architecture and to rewrite significant parts of the code, such as the back-end API or the front-end applications running on set-top boxes, on Android, or on iOS devices. They adopted a micro service architecture, deployed on Amazon Elastic Kubernetes Service (EKS) and written in the Go programming language for maximum performance. They designed a set of REST and GraphQL APIs to define the contracts between front and back-end applications, and an event-driven architecture with Apache Kafka for maximum scalability. They adopted multiple content delivery networks, including Amazon CloudFront, to reliably distribute the video streams to client devices. In August 2020, TF1 got a chance to test the new platform on a large-scale sporting event when Bayern Munich beat Paris Saint Germain 1-0 at the UEFA European Champion League.

TF1 headquarters in paris

Here’s a peek at what happens from the moment the action is shot on the field to the moment you see it on your mobile device: The high-quality video stream first lands in the TF1 tower, located in Paris, where hardware encoders create the necessary videos streams adapted to your device. AWS Elemental Live hardware encoders are able to generate up to eight different encodings: 4K for TVs, high-definition (1080), standard definition (720), and a variety of other formats suited to a wide range of mobile devices and network bandwidth. (This extra video encoding step is one of the reasons why you might sometimes observe a extra latency between the video you receive on your traditional TV and the feed you receive on your mobile device.) The system sends the encoded videos to AWS Elemental Media Package for packaging and, finally, to the CDNs where the player applications fetch the video segments. The player applications select the best video encoding depending on your device size and current network bandwidth available.

At the end of 2021, one year before millions watched French player Kylian Mbappé score a hat trick (three goals) for the first time in a World Cup final since 1966, TF1 started preparing for the big event by identifying risks based on previous experiences and areas needing improvement. Thierry described how they built hypotheses of the likely audience size based on different game scenarios: the longer the French national team might stay in the competition, the higher the expected traffic. They classified risks for each phase of the tournament (selection pools, quarter-final, semi-final, and final). Based on these scenarios, they figured that the platform must be able to sustain 4.5 million viewers connecting to the platform 15 minutes before the start of a game (that’s 5,000 new viewers every second).

This level of scalability requires preparation from TF1’s team but also all external systems in use, such as the AWS cloud services, the authentication and authorization service, and the CDN services.

A viewer arrival triggers multiple flows and API calls. The viewer must authenticate, and some must create a new account or reset their passwords. Once authenticated, the viewer sees the homepage that, in turn, triggers multiple API calls, one of them to the catalog service. When the viewer selects a live stream, other API calls are made to receive the video stream URL. Then the video part kicks in. The client-side player connects to the chosen CDN and starts to download video segments. Once the video is playing, the platform must ensure the stream is delivered smoothly, with high quality and no drop that would cause a re-buffering. All these elements are key to ensuring the best possible viewer experience.

The Preparation
Six months before France made it to the final and squared off against Argentina, TF1 started to work closely with their vendors, including AWS, to define requirements, reserve capacity, and start to work on test and execution plans. At this point, TF1 engaged with AWS Infrastructure Event Management, a dedicated program of the AWS enterprise support plan. Our experts offer architecture and guidance and operational support during the preparation and execution of planned events, such as shopping holidays, product launches, migrations – and in this case, the largest football (soccer) event in the world. For these events, AWS helps customers assess operational readiness, identify and mitigate risks, and execute confidently with AWS experts by their side.

Special care was given to test the scalability of the API. The TF1 team developped a load-testing engine to simulate users connecting to the platform, authenticating, selecting a program, and starting a video stream. To closely simulate real traffic, TF1 used another hyperscale cloud provider to send requests to their AWS infrastructure. The testing allowed them to define the correct metrics to observe in their dashboards and the correct values to generate alarms. Thierry said the first time the load simulator ran full speed, simulating 5,000 new connections per second, it crashed the entire back end.

But like any world class team, TF1 used this to their advantage. They took 2–3 weeks to tune the system. They eliminated redundant API calls from client applications and applied aggressive caching strategies. They learned how to scale their back-end platform in response to such traffic. They also learned to identify the value of key metrics under load. After a couple of back-end deployments and new releases for their Android and iOS apps, the system successfully passed the load test. It was a month before the start of the event. At that moment, TF1 decided to freeze all new developments or deployments until the first kickoff in Qatar, unless critical bugs were found.

Monitoring and Planning
The technological platform was only one piece of the project, Thierry told me. They also designed metric dashboards using Datadog and Grafana to monitor key performance indicators and detect anomalies during the event. Thierry noted that when observing average values, they often miss parts of the picture. For example, he said, observing a P95 percentile value instead of an average shows the experience for five percent of your users. When you have three million of them, five percent represents 150K customers, so it is important to know what their experience is. (Incidentally, this percentile technique is used routinely at Amazon and AWS across all service teams, and Amazon CloudWatch has built-in support to measure percentile values.)

TF1 also prepared for the worst, he said, including the specter of having three million people staring at a black screen during a game. TF1 involved community managers and social media owners early on, and they prepared press releases and social media messages for multiple scenarios. The team also planned to gather all key team members together in a “war room” during each game to reduce communication and reaction time if something needed immediate action. This team included the AWS technical account manager, their counterpart from the authentication service, and other CDN vendors. AWS also had on-call engineers from service teams and premium support team monitoring the health of our services and ready to react in case something went wrong.

The Attacks Weren’t Just on the Field
Three key moments at the start of the tournament provided opportunities to test the platform for real: the opening ceremony, the first game, and particularly for TF1’s audience, the first game for the French team. As the tournament played out over the following weeks — with increased intensity, suspense, and load on IT systems as the French team progressed — the TF1 team would reevaluate its traffic estimates and conduct debriefs after each game. But while the intensity of the action was unfolding on the field, TF1’s team had some behind-the-scenes excitement of its own.

Starting in the quarter final, the team noticed unusual activity from a wide range of distributed IP addresses, and they determined that the system was under a large distributed denial of service (DDOS) attack from a network of compromised machines; someone was trying to take down the service and prevent millions of people from watching. TF1 is accustomed to these types of attacks, and their dashboard helped to identify the traffic patterns in real time. Services such as AWS Shield and AWS Web Application Firewall helped to mitigate the incident without impacting the viewer experience. The TF1 security team and AWS experts conducted further analysis to proactively block some patterns of traffic and IP addresses for the next game.

Still, the intensity of the attacks increased during the semi-finals and final game, when it peaked at 40 millions of requests for a ten-minute period. “These attacks are a cat-and-mouse game,” said Thierry: attackers try new strategies and apply new patterns, but the team in the war room detects them and dynamically updates the filtering rules to block them before viewers can even detect a change in the quality of the service. The long and detailed preparation served its purpose, and everybody knew what to do. Thierry reported that the attacks were successfully mitigated with no consequences.

The Thrilling Finale
France ArgentineBy the time France took to the pitch on Dec. 18, 2022, TF1 knew they would break records on the platform. Thierry said the traffic was higher than estimated, but the platform absorbed it. He also described that during the first part of the game, when Argentina was leading, the TF1 team observed a slow decline of connections… that is, until the first goal scored by MBappé 10 minutes before the end of the game. At that point, all dashboards showed a sudden return of viewers for the thrilling last moments of the game. At peak, more than 3.2 million digital players were connected at the same time, delivering 3.6 terabits per second of outgoing bandwidth through all four CDNs.

Across the globe, Amazon CloudFront also helped 18 broadcasters deliver video streams. In all, over 48 million unique client IPs connected to one of 450+ edge locations globally during the tournament, peaking at just under 23 terabits per second across these customer distributions during the final game of the tournament.

The Future
While Argentina ultimately triumphed and Lionel Messi achieved his long-sought World Cup win, the 2022 FIFA World Cup proved to the team at TF1 that their processes, their architecture, and their implementation are able to deliver a high-quality viewing experience to millions. The team is now confident the platform is ready to absorb the next planned large-scale events: the World Cup of Rugby in September 2023 and the next French presidential election in 2027. Thierry concluded our conversation predicting digital broadcasting will eventually attain a larger audience than over-the-air, and having 3+ millions simultaneous viewers will become the new normal.

If your company is also looking to transform its business using the power of cloud computing, consult with one of our AWS Enterprise support advisors today.

— seb

Deep Pool boosts software quality control using Amazon QuickSight

Post Syndicated from Shruthi Panicker original https://aws.amazon.com/blogs/big-data/deep-pool-boosts-software-quality-control-using-amazon-quicksight/

Deep Pool Financial Solutions, an investor servicing and compliance solutions supplier, was looking to build key performance indicators to track its software tests, failures, and successful fixes to pinpoint the specific areas for improvement in its client software. Deep Pool was unable to access the large amounts of data that its project management software provided, so it used AWS to access, manage, and analyze that data more efficiently.

During a larger migration to the AWS Cloud, the company discovered Amazon QuickSight, a cloud-native, serverless business intelligence (BI) service that powers interactive dashboards that let companies make better data-driven decisions. With QuickSight, Deep Pool could democratize access to this unused data and pinpoint areas for improvement in its software development processes, thereby improving the overall quality of its software.

According to Brett Promisel, Chief Operating Officer for Deep Pool, the company wanted to manage the data that it was collecting from a BI point of view to help it make more informed decisions. Because word of mouth and high-quality software are critical in Deep Pool’s industry, the company wanted to add additional rigorous quality controls to its product development and testing so that it continues to provide top-notch, stable software that its clients can rely on.

In this post, we share how Deep Pool boosted its software quality control using QuickSight.

Enhancing software testing to with data-driven insights

Continuous improvement is a hallmark of leading organizations. Deep Pool wanted achieve greater software quality and decided to improve how it monitored and managed its software testing processes using data.

Typical development processes involve extensive testing. First, the original developer tests the code, and then the code is unit tested. Next, larger groups test the code. For all this testing to be successful and result in product improvement, it needs to be measured and tracked so that developers can learn from it and implement improvements during the development process.

Using QuickSight for data-driven insights, Deep Pool has implemented significant software testing and control. It can now count the number of bugs found or tests failed and time how long it took to create patches and repair issues. It can also better track its work backlog and the progress of functionality requests. Monitoring this information lets the company know that it has successfully implemented improvements, because a decreasing number of bugs over time is a strong indicator of quality control.

Monitoring development to increase efficiency

Better software test management benefits two groups: internal teams and external customers. Deep Pool can now log and communicate important information, such as when a request is made, how it’s being resolved or addressed, and how it’s being tested. In addition to helping internal teams streamline their processes, the company can also use this data to track communications with customers, which are also stored in its project management software. Such knowledge helps the company determine whether customer requests are being promptly addressed and identify common trends that require action on a larger scale.

Seven development teams at Deep Pool independently write the code for the components of the company’s software products, and they must integrate those components to create the final products. With the granularity of the data that is provided by QuickSight, Deep Pool can thoroughly analyze the development and testing of these products. The company now has the ability to trace software bugs down to their original coding, which makes it simple to quickly locate and address any issues that come up. Deep Pool can also measure the results of those mitigating actions and determine whether its repairs were successful.

Attention to detail helps Deep Pool improve software quality, leading to better products and customers who are more likely to give positive referrals.

“Amazon QuickSight is extremely valuable to us when performing quality control. We can now expose our whole development team to how we’re managing databases and servers and measuring performance in a more optimal way,” says Promisel.

Deep Pool has successfully proven that it can use QuickSight to measure its quality control to improve its software and, ultimately, better support its customers. Since the migration to AWS, the number of software issues discovered and logged has dropped by 57%.

The increased quality control that has come from the company’s focus on accessing all its data and optimizing its use has led to better efficiency, which results in the ability to expand its growth without increasing its costs.

“We should be able to increase our customer base without adding the equivalent costs. Making sure we are as efficient as possible lets me manage that way,” says Promisel.

Expanding into more data sources

Deep Pool is also exploring how to expand its use of QuickSight to extract and use data from even more of its databases. In the future, it hopes to analyze its internal metrics, such as sales data, and its external client-related information, such as assets and holdings, to guide how it builds its client software and provides even more custom products.

Deep Pool is also committed to helping its employees be innovative and successful by investing in their futures and skill sets. It understands that well-trained employees can optimize the use of their tools, which results in better products. As such, the company will continue to invest in the training offered by AWS. Using cutting-edge tools and promoting its intent to invest in its employees indicate to Deep Pool’s customers that the company plans to stay innovative and ahead of the technological curve.

To learn more about how QuickSight can help your business with dashboards, reports, and more, visit Amazon QuickSight.


About the Author

Shruthi Panicker is a Senior Product Marketing Manager with Amazon QuickSight at AWS. As an engineer turned product marketer, Shruthi has spent over 15 years in the technology industry in various roles from software engineering, to solution architecting to product marketing. She is passionate about working at the intersection of technology and business to tell great product stories that help drive customer value.

Building diversified and cost-optimized EC2 server groups in Spinnaker

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/building-diversified-and-cost-optimized-ec2-server-groups-in-spinnaker/

This blog post is written by Sandeep Palavalasa, Sr. Specialist Containers SA, and Prathibha Datta-Kumar, Software Development Engineer

Spinnaker is an open source continuous delivery platform created by Netflix for releasing software changes rapidly and reliably. It enables teams to automate deployments into pipelines that are run whenever a new version is released with proven deployment strategies that are faster and more dependable with zero downtime. For many AWS customers, Spinnaker is a critical piece of technology that allows developers to deploy their applications safely and reliably across different AWS managed services.

Listening to customer requests on the Spinnaker open source project and in the Amazon EC2 Spot Instances integrations roadmap, we have further enhanced Spinnaker’s ability to deploy on Amazon Elastic Compute Cloud (Amazon EC2). The enhancements make it easier to combine Spot Instances with On-Demand, Reserved, and Savings Plans Instances to optimize workload costs with performance. You can improve workload availability when using Spot Instances with features such as allocation strategies and proactive Spot capacity rebalancing, when you are flexible about Instance types and Availability Zones. Combinations of these features offer the best possible experience when using Amazon EC2 with Spinnaker.

In this post, we detail the recent enhancements, along with a walkthrough of how you can use them following the best practices.

Amazon EC2 Spot Instances

EC2 Spot Instances are spare compute capacity in the AWS Cloud available at steep discounts of up to 90% when compared to On-Demand Instance prices. The primary difference between an On-Demand Instance and a Spot Instance is that a Spot Instance can be interrupted by Amazon EC2 with a two-minute notification when Amazon EC2 needs the capacity back. Amazon EC2 now sends rebalance recommendation notifications when Spot Instances are at an elevated risk of interruption. This signal can arrive sooner than the two-minute interruption notice. This lets you proactively replace your Spot Instances before it’s interrupted.

The best way to adhere to Spot best practices and instance fleet management is by using an Amazon EC2 Auto Scaling group When using Spot Instances in Auto Scaling group, enabling Capacity Rebalancing helps you maintain workload availability by proactively augmenting your fleet with a new Spot Instance before a running instance is interrupted by Amazon EC2.

Spinnaker concepts

Spinnaker uses three key concepts to describe your services, including applications, clusters, and server groups, and how your services are exposed to users is expressed as Load balancers and firewalls.

An application is a collection of clusters, a cluster is a collection of server groups, and a server group identifies the deployable artifact and basic configuration settings such as the number of instances, autoscaling policies, metadata, etc. This corresponds to an Auto Scaling group in AWS. We use Auto Scaling groups and server groups interchangeably in this post.

Spinnaker and Amazon EC2 Integration

In mid-2020, we started looking into customer requests and gaps in the Amazon EC2 feature set supported in Spinnaker. Around the same time, Spinnaker OSS added support for Amazon EC2 Launch Templates. Thanks to their effort, we could follow-up and expand the Amazon EC2 feature set supported in Spinnaker. Now that we understand the new features, let’s look at how to use some of them in the following tutorial spinnaker.io.

Here are some highlights of the features contributed recently:

Feature Why use it? (Example use cases)
  Multiple Instance Types   Tap into multiple capacity pools to achieve and maintain the desired scale using Spot Instances.
  Combining On-Demand and Spot Instances

  – Control the proportion of On-Demand and Spot Instances launched in your sever group.

– Combine Spot Instances with Amazon EC2 Reserved Instances or Savings Plans.

  Amazon EC2 Auto Scaling allocation strategies   Reduce overall Spot interruptions by launching from Spot pools that are optimally chosen based on the available Spot capacity, using capacity-optimized Spot allocation strategy.
  Capacity rebalancing   Improve your workload availability by proactively shifting your Spot capacity to optimal pools by enabling capacity rebalancing along with capacity-optimized allocation strategy.
  Improved support for burstable performance instance types with custom credit specification   Reduce costs by preventing wastage of CPU cycles.

We recommend using Spinnaker stable release 1.28.x for API users and 1.29.x for UI users. Here is the Git issue for related PRs and feature releases.

Now that we understand the new features, let’s look at how to use some of them in the following tutorial.

Example tutorial: Deploy a demo web application on an Auto Scaling group with On-Demand and Spot Instances

In this example tutorial, we setup Spinnaker to deploy to Amazon EC2, create an Application Load Balancer, and deploy a demo application on a server group diversified across multiple instance types and purchase options – this case On-Demand and Spot Instances.

We leverage Spinnaker’s API throughout the tutorial to create new resources, along with a quick guide on how to deploy the same using Spinnaker UI (Deck) and leverage UI to view them.

Prerequisites

As a prerequisite to complete this tutorial, you must have an AWS Account with an AWS Identity and Access Management (IAM) User that has the AdministratorAccess configured to use with AWS Command Line Interface (AWS CLI).

1. Spinnaker setup

We will use the AWS CloudFormation template setup-spinnaker-with-deployment-vpc.yml to setup Spinnaker and the required resources.

1.1 Create an Secure Shell(SSH) keypair used to connect to Spinnaker and EC2 instances launched by Spinnaker.

AWS_REGION=us-west-2 # Change the region where you want Spinnaker deployed
EC2_KEYPAIR_NAME=spinnaker-blog-${AWS_REGION}
aws ec2 create-key-pair --key-name ${EC2_KEYPAIR_NAME} --region ${AWS_REGION} --query KeyMaterial --output text > ~/${EC2_KEYPAIR_NAME}.pem
chmod 600 ~/${EC2_KEYPAIR_NAME}.pem

1.2 Deploy the Cloudformation stack.

STACK_NAME=spinnaker-blog
SPINNAKER_VERSION=1.29.1 # Change the version if newer versions are available
NUMBER_OF_AZS=3
AVAILABILITY_ZONES=${AWS_REGION}a,${AWS_REGION}b,${AWS_REGION}c
ACCOUNT_ID=$(aws sts get-caller-identity --query "Account" --output text)
S3_BUCKET_NAME=spin-persitent-store-${ACCOUNT_ID}

# Download template
curl -o setup-spinnaker-with-deployment-vpc.yml https://raw.githubusercontent.com/awslabs/ec2-spot-labs/master/ec2-spot-spinnaker/setup-spinnaker-with-deployment-vpc.yml

# deploy stack
aws cloudformation deploy --template-file setup-spinnaker-with-deployment-vpc.yml \
    --stack-name ${STACK_NAME} \
    --parameter-overrides NumberOfAZs=${NUMBER_OF_AZS} \
    AvailabilityZones=${AVAILABILITY_ZONES} \
    EC2KeyPairName=${EC2_KEYPAIR_NAME} \
    SpinnakerVersion=${SPINNAKER_VERSION} \
    SpinnakerS3BucketName=${S3_BUCKET_NAME} \
    --capabilities CAPABILITY_NAMED_IAM --region ${AWS_REGION}

1.3 Connecting to Spinnaker

1.3.1 Get the SSH command to port forwarding for Deck – the browser-based UI (9000) and Gate – the API Gateway (8084) to access the Spinnaker UI and API.

SPINNAKER_INSTANCE_DNS_NAME=$(aws cloudformation describe-stacks --stack-name ${STACK_NAME} --region ${AWS_REGION} --query "Stacks[].Outputs[?OutputKey=='SpinnakerInstance'].OutputValue" --output text)
echo 'ssh -A -L 9000:localhost:9000 -L 8084:localhost:8084 -L 8087:localhost:8087 -i ~/'${EC2_KEYPAIR_NAME}' ubuntu@$'{SPINNAKER_INSTANCE_DNS_NAME}''

1.3.2 Open a new terminal and use the SSH command (output from the previous command) to connect to the Spinnaker instance. After you successfully connect to the Spinnaker instance via SSH, access the Spinnaker UI here and API here.

2. Deploy a demo web application

Let’s make sure that we have the environment variables required in the shell before proceeding. If you’re using the same terminal window as before, then you might already have these variables.

STACK_NAME=spinnaker-blog
AWS_REGION=us-west-2 # use the same region as before
EC2_KEYPAIR_NAME=spinnaker-blog-${AWS_REGION}
VPC_ID=$(aws cloudformation describe-stacks --stack-name ${STACK_NAME} --region ${AWS_REGION} --query "Stacks[].Outputs[?OutputKey=='VPCID'].OutputValue" --output text)

2.1 Create a Spinnaker Application

We start by creating an application in Spinnaker, a placeholder for the service that we deploy.

curl 'http://localhost:8084/tasks' \
-H 'Content-Type: application/json;charset=utf-8' \
--data-raw \
'{
   "job":[
      {
         "type":"createApplication",
         "application":{
            "cloudProviders":"aws",
            "instancePort":80,
            "name":"demoapp",
            "email":"[email protected]",
            "providerSettings":{
               "aws":{
                  "useAmiBlockDeviceMappings":true
               }
            }
         }
      }
   ],
   "application":"demoapp",
   "description":"Create Application: demoapp"
}'

Spin Create Server Group

2.2 Create an Application Load Balancer

Let’s create an Application Load Balanacer and a target group for port 80, spanning the three availability zones in our public subnet. We use the Demo-ALB-SecurityGroup for Firewalls to allow public access to the ALB on port 80.

As Spot Instances are interrupted with a two minute warning, you must adjust the Target Group’s deregistration delay to a slightly lower time. Recommended values are 90 seconds or less. This allows time for in-flight requests to complete and gracefully close existing connections before the instance is interrupted.

curl 'http://localhost:8084/tasks' \
-H 'Content-Type: application/json;charset=utf-8' \
--data-binary \
'{
   "application":"demoapp",
   "description":"Create Load Balancer: demoapp",
   "job":[
      {
         "type":"upsertLoadBalancer",
         "name":"demoapp-lb",
         "loadBalancerType":"application",
         "cloudProvider":"aws",
         "credentials":"my-aws-account",
         "region":"'"${AWS_REGION}"'",
         "vpcId":"'"${VPC_ID}"'",
         "subnetType":"public-subnet",
         "idleTimeout":60,
         "targetGroups":[
            {
               "name":"demoapp-targetgroup",
               "protocol":"HTTP",
               "port":80,
               "targetType":"instance",
               "healthCheckProtocol":"HTTP",
               "healthCheckPort":"traffic-port",
               "healthCheckPath":"/",
               "attributes":{
                  "deregistrationDelay":90
               }
            }
         ],
         "regionZones":[
            "'"${AWS_REGION}"'a",
            "'"${AWS_REGION}"'b",
            "'"${AWS_REGION}"'c"
         ],
         "securityGroups":[
            "Demo-ALB-SecurityGroup"
         ],
         "listeners":[
            {
               "protocol":"HTTP",
               "port":80,
               "defaultActions":[
                  {
                     "type":"forward",
                     "targetGroupName":"demoapp-targetgroup"
                 }
               ]
            }
         ]
      }
   ]
}'

Spin Create ALB

2.3 Create a server group

Before creating a server group (Auto Scaling group), here is a brief overview of the features used in the example:

      • onDemandBaseCapacity (default 0): The minimum amount of your ASG’s capacity that must be fulfilled by On-Demand instances (can also be applied toward Reserved Instances or Savings Plans). The example uses an onDemandBaseCapacity of three.
      • onDemandPercentageAboveBaseCapacity (default 100): The percentages of On-Demand and Spot Instances for additional capacity beyond OnDemandBaseCapacity. The example uses onDemandPercentageAboveBaseCapacity of 10% (i.e. 90% Spot).
      • spotAllocationStrategy: This indicates how you want to allocate instances across Spot Instance pools in each Availability Zone. The example uses the recommended Capacity Optimized strategy. Instances are launched from optimal Spot pools that are chosen based on the available Spot capacity for the number of instances that are launching.
      • launchTemplateOverridesForInstanceType: The list of instance types that are acceptable for your workload. Specifying multiple instance types enables tapping into multiple instance pools in multiple Availability Zones, designed to enhance your service’s availability. You can use the ec2-instance-selector, an open source AWS Command Line Interface(CLI) tool to narrow down the instance types based on resource criteria like vcpus and memory.
      • capacityRebalance: When enabled, this feature proactively manages the EC2 Spot Instance lifecycle leveraging the new EC2 Instance rebalance recommendation. This increases the emphasis on availability by automatically attempting to replace Spot Instances in an ASG before they are interrupted by Amazon EC2. We enable this feature in this example.

Learn more on spinnaker.io: feature descriptions and use cases and sample API requests.

Let’s create a server group with a desired capacity of 12 instances diversified across current and previous generation instance types, attach the previously created ALB, use Demo-EC2-SecurityGroup for the Firewalls which allows http traffic only from the ALB, use the following bash script for UserData to install httpd, and add instance metadata into the index.html.

2.3.1 Save the userdata bash script into a file user-date.sh.

Note that Spinnaker only support base64 encoded userdata. We use base64 bash command to encode the file contents in the next step.

cat << "EOF" > user-data.sh
#!/bin/bash
yum update -y
yum install httpd -y
echo "<html>
    <head>
        <title>Demo Application</title>
        <style>body {margin-top: 40px; background-color: #Gray;} </style>
    </head>
    <body>
        <h2>You have reached a Demo Application running on</h2>
        <ul>
            <li>instance-id: <b> `curl http://169.254.169.254/latest/meta-data/instance-id` </b></li>
            <li>instance-type: <b> `curl http://169.254.169.254/latest/meta-data/instance-type` </b></li>
            <li>instance-life-cycle: <b> `curl http://169.254.169.254/latest/meta-data/instance-life-cycle` </b></li>
            <li>availability-zone: <b> `curl http://169.254.169.254/latest/meta-data/placement/availability-zone` </b></li>
        </ul>
    </body>
</html>" > /var/www/html/index.html
systemctl start httpd
systemctl enable httpd
EOF

2.3.2 Create the server group by running the following command. Note we use the KeyPairName that we created as part of the prerequisites.

curl 'http://localhost:8084/tasks' \
-H 'Content-Type: application/json;charset=utf-8' \
-d \
'{
   "job":[
      {
         "type":"createServerGroup",
         "cloudProvider":"aws",
         "account":"my-aws-account",
         "application":"demoapp",
         "stack":"",
         "credentials":"my-aws-account",
	"healthCheckType": "ELB",
	"healthCheckGracePeriod":600,
	"capacityRebalance": true,
         "onDemandBaseCapacity":3, 
         "onDemandPercentageAboveBaseCapacity":10,
         "spotAllocationStrategy":"capacity-optimized",
         "setLaunchTemplate":true,
         "launchTemplateOverridesForInstanceType":[
            {
               "instanceType":"m4.large"
            },
            {
               "instanceType":"m5.large"
            },
            {
               "instanceType":"m5a.large"
            },
            {
               "instanceType":"m5ad.large"
            },
            {
               "instanceType":"m5d.large"
            },
            {
               "instanceType":"m5dn.large"
            },
            {
               "instanceType":"m5n.large"
            }

         ],
         "capacity":{
            "min":6,
            "max":21,
            "desired":12
         },
         "subnetType":"private-subnet",
         "availabilityZones":{
            "'"${AWS_REGION}"'":[
               "'"${AWS_REGION}"'a",
               "'"${AWS_REGION}"'b",
               "'"${AWS_REGION}"'c"
            ]
         },
         "keyPair":"'"${EC2_KEYPAIR_NAME}"'",
         "securityGroups":[
            "Demo-EC2-SecurityGroup"
         ],
         "instanceType":"m5.large",
         "virtualizationType":"hvm",
         "amiName":"'"$(aws ec2 describe-images --owners amazon --filters "Name=name,Values=amzn2-ami-hvm-2*x86_64-gp2" --query 'reverse(sort_by(Images, &CreationDate))[0].Name' --region ${AWS_REGION} --output text)"'",
         "targetGroups":[
            "demoapp-targetgroup"
         ],
         "base64UserData":"'"$(base64 user-data.sh)"'",,
        "associatePublicIpAddress":false,
         "instanceMonitoring":false
      }
   ],
   "application":"demoapp",
   "description":"Create New server group in cluster demoapp"
}'

Spin Create ServerGroup

Spinnaker creates an Amazon EC2 Launch Template and an ASG with specified parameters and waits until the ALB health check passes before sending traffic to the EC2 Instances.

The server group and launch template that we just created will look like this in Spinnaker UI:

Spin View ServerGroup

The UI also displays capacity type, such as the purchase option for each instance type in the Instance Information section:

Spin View ServerGroup Purchase Options 1Spin View ServerGroup Purchase Options 2

3. Access the application

Copy the Application Load Balancer URL by selecting the tree icon in the right top corner of the server group, and access it in a browser. You can refresh multiple times to see that the requests are going to different instances every time.

Spin Access App

Congratulations! You successfully deployed the demo application on an Amazon EC2 server group diversified across multiple instance types and purchase options.

Moreover, you can clone, modify, disable, and destroy these server groups, as well as use them with Spinnaker pipelines to effectively release new versions of your application.

Cost savings

Check the savings you realized by deploying your demo application on EC2 Spot Instances by going to EC2 console > Spot Requests > Saving Summary.

Spin Spot Savings

Cleanup

To avoid incurring any additional charges, clean up the resources created in the tutorial.

Frist, delete the server group, application load balancer and application in Spinnaker.

curl 'http://localhost:8084/tasks' \
-H 'Content-Type: application/json;charset=utf-8' \
--data-raw \
'{
   "job":[
      {
         "reason":"Cleanup",
         "asgName":"demoapp-v000",
         "moniker":{
            "app":"demoapp",
            "cluster":"demoapp",
            "sequence":0
         },
         "serverGroupName":"demoapp-v000",
         "type":"destroyServerGroup",
         "region":"'"${AWS_REGION}"'",
         "credentials":"my-aws-account",
         "cloudProvider":"aws"
      },
      {
         "cloudProvider":"aws",
         "loadBalancerName":"demoapp-lb",
         "loadBalancerType":"application",
         "regions":[
            "'"${AWS_REGION}"'"
         ],
         "credentials":"my-aws-account",
         "vpcId":"'"${VPC_ID}"'",
         "type":"deleteLoadBalancer"
      },
      {
         "type":"deleteApplication",
         "application":{
            "name":"demoapp",
            "cloudProviders":"aws"
         }
      }
   ],
   "application":"demoapp",
   "description":"Deleting ServerGroup, ALB and Application: demoapp"
}'

Wait for Spinnaker to delete all of the resources before proceeding further. You can confirm this either on the Spinnaker UI or AWS Management Console.

Then delete the Spinnaker infrastructure by running the following command:

aws ec2 delete-key-pair --key-name ${EC2_KEYPAIR_NAME} --region ${AWS_REGION}
rm ~/${EC2_KEYPAIR_NAME}.pem
aws s3api delete-objects \
--bucket ${S3_BUCKET_NAME} \
--delete "$(aws s3api list-object-versions \
--bucket ${S3_BUCKET_NAME} \
--query='{Objects: Versions[].{Key:Key,VersionId:VersionId}}')" #If error occurs, there are no Versions and is OK
aws s3api delete-objects \
--bucket ${S3_BUCKET_NAME} \
--delete "$(aws s3api list-object-versions \
--bucket ${S3_BUCKET_NAME} \
--query='{Objects: DeleteMarkers[].{Key:Key,VersionId:VersionId}}')" #If error occurs, there are no DeleteMarkers and is OK
aws s3 rb s3://${S3_BUCKET_NAME} --force #Delete Bucket
aws cloudformation delete-stack --region ${AWS_REGION} --stack-name ${STACK_NAME}

Conclusion

In this post, we learned about the new Amazon EC2 features recently added to Spinnaker, and how to use them to build diversified and optimized Auto Scaling Groups. We also discussed recommended best practices for EC2 Spot and how they can improve your experience with it.

We would love to hear from you! Tell us about other Continuous Integration/Continuous Delivery (CI/CD) platforms that you want to use with EC2 Spot and/or Auto Scaling Groups by adding an issue on the Spot integrations roadmap.

Unit Testing AWS Lambda with Python and Mock AWS Services

Post Syndicated from Kevin Hakanson original https://aws.amazon.com/blogs/devops/unit-testing-aws-lambda-with-python-and-mock-aws-services/

When building serverless event-driven applications using AWS Lambda, it is best practice to validate individual components.  Unit testing can quickly identify and isolate issues in AWS Lambda function code.  The techniques outlined in this blog demonstrates unit test techniques for Python-based AWS Lambda functions and interactions with AWS Services.

The full code for this blog is available in the GitHub project as a demonstrative example.

Example use case

Let’s consider unit testing a serverless application which provides an API endpoint to generate a document.  When the API endpoint is called with a customer identifier and document type, the Lambda function retrieves the customer’s name from DynamoDB, then retrieves the document text from DynamoDB for the given document type, finally generating and writing the resulting document to S3.

Figure 1. Example application architecture

Figure 1. Example application architecture

  1. Amazon API Gateway provides an endpoint to request the generation of a document for a given customer.  A document type and customer identifier are provided in this API call.
  2. The endpoint invokes an AWS Lambda function that generates a document using the customer identifier and the document type provided.
  3. An Amazon DynamoDB table stores the contents of the documents and the users name, which are retrieved by the Lambda function.
  4. The resulting text document is stored to Amazon S3.

Our testing goal is to determine if an isolated “unit” of code works as intended. In this blog, we will be writing tests to provide confidence that the logic written in the above AWS Lambda function behaves as we expect. We will mock the service integrations to Amazon DynamoDB and S3 to isolate and focus our tests on the Lambda function code, and not on the behavior of the AWS Services.

Define the AWS Service resources in the Lambda function

Before writing our first unit test, let’s look at the Lambda function that contains the behavior we wish to test.  The full code for the Lambda function is available in the GitHub repository as src/sample_lambda/app.py.

As part of our Best practices for working AWS Lambda functions, we recommend initializing AWS service resource connections outside of the handler function and in the global scope.  Additionally, we can retrieve any relevant environment variables in the global scope so that subsequent invocations of the Lambda function do not repeatedly need to retrieve them.  For organization, we can put the resource and variables in a dictionary:

_LAMBDA_DYNAMODB_RESOURCE = { "resource" : resource('dynamodb'), 
                              "table_name" : environ.get("DYNAMODB_TABLE_NAME","NONE") }

However, globally scoped code and global variables are challenging to test in Python, as global statements are executed on import, and outside of the controlled test flow.  To facilitate testing, we define classes for supporting AWS resource connections that we can override (patch) during testing.  These classes will accept a dictionary containing the boto3 resource and relevant environment variables.

For example, we create a DynamoDB resource class with a parameter “boto3_dynamodb_resource” that accepts a boto3 resource connected to DynamoDB:

class LambdaDynamoDBClass:
    def __init__(self, lambda_dynamodb_resource):
        self.resource = lambda_dynamodb_resource["resource"]
        self.table_name = lambda_dynamodb_resource["table_name"]
        self.table = self.resource.Table(self.table_name)

Build the Lambda Handler

The Lambda function handler is the method in the AWS Lambda function code that processes events. When the function is invoked, Lambda runs the handler method. When the handler exits or returns a response, it becomes available to process another event.

To facilitate unit test of the handler function, move as much of logic as possible to other functions that are then called by the Lambda hander entry point.  Also, pass the AWS resource global variables to these subsequent function calls.  This approach enables us to mock and intercept all resources and calls during test.

In our example, the handler references the global variables, and instantiates the resource classes to setup the connections to specific AWS resources.  (We will be able to override and mock these connections during unit test.)

Then the handler calls the create_letter_in_s3 function to perform the steps of creating the document, passing the resource classes.  This downstream function avoids directly referencing the global context or any AWS resource connections directly.

def lambda_handler(event: APIGatewayProxyEvent, context: LambdaContext) -> Dict[str, Any]:

    global _LAMBDA_DYNAMODB_RESOURCE
    global _LAMBDA_S3_RESOURCE

    dynamodb_resource_class = LambdaDynamoDBClass(_LAMBDA_DYNAMODB_RESOURCE)
    s3_resource_class = LambdaS3Class(_LAMBDA_S3_RESOURCE)

    return create_letter_in_s3(
            dynamo_db = dynamodb_resource_class,
            s3 = s3_resource_class,
            doc_type = event["pathParameters"]["docType"],
            cust_id = event["pathParameters"]["customerId"])

Unit testing with mock AWS services

Our Lambda function code has now been written and is ready to be tested, let’s take a look at the unit test code!   The full code for the unit test is available in the GitHub repository as tests/unit/src/test_sample_lambda.py.

In production, our Lambda function code will directly access the AWS resources we defined in our function handler; however, in our unit tests we want to isolate our code and replace the AWS resources with simulations.  This isolation facilitates running unit tests in an isolated environment to prevent accidental access to actual cloud resources.

Moto is a python library for Mocking AWS Services that we will be using to simulate AWS resource our tests.  Moto supports many AWS resources, and it allows you to test your code with little or no modification by emulating functionality of these services.

Moto uses decorators to intercept and simulate responses to and from AWS resources.  By adding a decorator for a given AWS service, subsequent calls from the module to that service will be re-directed to the mock.

@moto.mock_dynamodb
@moto.mock_s3

Configure Test Setup and Tear-down

The mocked AWS resources will be used during the unit test suite.  Using the setUp() method allows you to define and configure the mocked global AWS Resources before the tests are run.

We define the test class and a setUp() method and initialize the mock AWS resource.  This includes configuring the resource to prepare it for testing, such as defining a mock DynamoDB table or creating a mock S3 Bucket.

class TestSampleLambda(TestCase):
    def setUp(self) -> None:
        dynamodb = boto3.resource("dynamodb", region_name="us-east-1")
        dynamodb.create_table(
            TableName = self.test_ddb_table_name,
            KeySchema = [{"AttributeName": "PK", "KeyType": "HASH"}],
            AttributeDefinitions = [{"AttributeName": "PK", 
                                     "AttributeType": "S"}],
            BillingMode = 'PAY_PER_REQUEST'
           
        s3_client = boto3.client('s3', region_name="us-east-1")
        s3_client.create_bucket(Bucket = self.test_s3_bucket_name ) 

After creating the mocked resources, the setup function creates resource class object referencing those mocked resources, which will be used during testing.

        mocked_dynamodb_resource = resource("dynamodb")
        mocked_s3_resource = resource("s3")
        mocked_dynamodb_resource = { "resource" : resource('dynamodb'),
                                     "table_name" : self.test_ddb_table_name  }
        mocked_s3_resource = { "resource" : resource('s3'),
                               "bucket_name" : self.test_s3_bucket_name }
        self.mocked_dynamodb_class = LambdaDynamoDBClass(mocked_dynamodb_resource)
        self.mocked_s3_class = LambdaS3Class(mocked_s3_resource)

Test #1: Verify the code writes the document to S3

Our first test will validate our Lambda function writes the customer letter to an S3 bucket in the correct manner.  We will follow the standard test format of arrange, act, assert when writing this unit test.

Arrange the data we need in the DynamoDB table:

def test_create_letter_in_s3(self) -> None:
    
    self.mocked_dynamodb_class.table.put_item(Item={"PK":"D#UnitTestDoc",
                                                        "data":"Unit Test Doc Corpi"})
    self.mocked_dynamodb_class.table.put_item(Item={"PK":"C#UnitTestCust",
                                                        "data":"Unit Test Customer"})

Act by calling the create_letter_in_s3 function.  During these act calls, the test passes the AWS resources as created in the setUp().

    test_return_value = create_letter_in_s3(
                        dynamo_db = self.mocked_dynamodb_class,
                        s3=self.mocked_s3_class,
                        doc_type = "UnitTestDoc",
                        cust_id = "UnitTestCust"
                        )

Assert by reading the data written to the mock S3 bucket, and testing conformity to what we are expecting:

bucket_key = "UnitTestCust/UnitTestDoc.txt"
    body = self.mocked_s3_class.bucket.Object(bucket_key).get()['Body'].read()

    self.assertEqual(test_return_value["statusCode"], 200)
    self.assertIn("UnitTestCust/UnitTestDoc.txt", test_return_value["body"])
    self.assertEqual(body.decode('ascii'),"Dear Unit Test Customer;\nUnit Test Doc Corpi")

Tests #2 and #3: Data not found error conditions

We can also test error conditions and handling, such as keys not found in the database.  For example, if a customer identifier is submitted, but does not exist in the database lookup, does the logic handle this and return a “Not Found” code of 404?

To test this in test #2, we add data to the mocked DynamoDB table, but then submit a customer identifier that is not in the database.

This test, and a similar test #3 for “Document Types not found”, are implemented in the example test code on GitHub.

Test #4: Validate the handler interface

As the application logic resides in independently tested functions, the Lambda handler function provides only interface validation and function call orchestration.  Therefore, the test for the handler validates that the event is parsed correctly, any functions are invoked as expected, and the return value is passed back.

To emulate the global resource variables and other functions, patch both the global resource classes and logic functions.

    @patch("src.sample_lambda.app.LambdaDynamoDBClass")
    @patch("src.sample_lambda.app.LambdaS3Class")
    @patch("src.sample_lambda.app.create_letter_in_s3")
    def test_lambda_handler_valid_event_returns_200(self,
                            patch_create_letter_in_s3 : MagicMock,
                            patch_lambda_s3_class : MagicMock,
                            patch_lambda_dynamodb_class : MagicMock
                            ):

Arrange for the test by setting return values for the patched objects.

patch_lambda_dynamodb_class.return_value = self.mocked_dynamodb_class
        patch_lambda_s3_class.return_value = self.mocked_s3_class

        return_value_200 = {"statusCode" : 200, "body":"OK"}
        patch_create_letter_in_s3.return_value = return_value_200

We need to provide event data when invoking the Lambda handler.  A good practice is to save test events as separate JSON files, rather than placing them inline as code. In the example project, test events are located in the folder “tests/events/”. During test execution, the event object is created from the JSON file using the utility function named load_sample_event_from_file.

test_event = self.load_sample_event_from_file("sampleEvent1")

Act by calling the lambda_handler function.

test_return_value = lambda_handler(event=test_event, context=None)

Assert by ensuring the create_letter_in_s3 function is called with the expected parameters based on the event, and a create_letter_in_s3 function return value is passed back to the caller.  In our example, this value is simply passed with no alterations.

patch_create_letter_in_s3.assert_called_once_with(
                                        dynamo_db=self.mocked_dynamodb_class,
                                        s3=self.mocked_s3_class,
                                        doc_type=test_event["pathParameters"]["docType"],
                                        cust_id=test_event["pathParameters"]["customerId"])

       self.assertEqual(test_return_value, return_value_200)

Tear Down

The tearDown() method is called immediately after the test method has been run and the result is recorded.  In our example tearDown() method, we clean up any data or state created so the next test won’t be impacted.

Running the unit tests

The unittest Unit testing framework can be run using the Python pytest utility.  To ensure network isolation and verify the unit tests are not accidently connecting to AWS resources, the pytest-socket project provides the ability to disable network communication during a test.

pytest -v --disable-socket -s tests/unit/src/

The pytest command results in a PASSED or FAILED status for each test.  A PASSED status verifies that your unit tests, as written, did not encounter errors or issues,

Conclusion

Unit testing is a software development process in which different parts of an application, called units, are individually and independently tested. Tests validate the quality of the code and confirm that it functions as expected. Other developers can gain familiarity with your code base by consulting the tests. Unit tests reduce future refactoring time, help engineers get up to speed on your code base more quickly, and provide confidence in the expected behaviour.

We’ve seen in this blog how to unit test AWS Lambda functions and mock AWS Services to isolate and test individual logic within our code.

AWS Lambda Powertools for Python has been used in the project to validate hander events.   Powertools provide a suite of utilities for AWS Lambda functions to ease adopting best practices such as tracing, structured logging, custom metrics, idempotency, batching, and more.

Learn more about AWS Lambda testing in our prescriptive test guidance, and find additional test examples on GitHub.  For more serverless learning resources, visit Serverless Land.

About the authors:

Tom Romano

Tom Romano is a Solutions Architect for AWS World Wide Public Sector from Tampa, FL, and assists GovTech and EdTech customers as they create new solutions that are cloud-native, event driven, and serverless. He is an enthusiastic Python programmer for both application development and data analytics. In his free time, Tom flies remote control model airplanes and enjoys vacationing with his family around Florida and the Caribbean.

Kevin Hakanson

Kevin Hakanson is a Sr. Solutions Architect for AWS World Wide Public Sector based in Minnesota. He works with EdTech and GovTech customers to ideate, design, validate, and launch products using cloud-native technologies and modern development practices. When not staring at a computer screen, he is probably staring at another screen, either watching TV or playing video games with his family.

Integrating with GitHub Actions – Amazon CodeGuru in your DevSecOps Pipeline

Post Syndicated from Mahesh Biradar original https://aws.amazon.com/blogs/devops/integrating-with-github-actions-amazon-codeguru-in-your-devsecops-pipeline/

Many organizations have adopted DevOps practices to streamline and automate software delivery and IT operations. A DevOps model can be adopted without sacrificing security by using automated compliance policies, fine-grained controls, and configuration management techniques. However, one of the key challenges customers face is analyzing code and detecting any vulnerabilities in the code pipeline due to a lack of access to the right tool. Amazon CodeGuru addresses this challenge by using machine learning and automated reasoning to identify critical issues and hard-to-find bugs during application development and deployment, thus improving code quality.

We discussed how you can build a CI/CD pipeline to deploy a web application in our previous post “Integrating with GitHub Actions – CI/CD pipeline to deploy a Web App to Amazon EC2”. In this post, we will use that pipeline to include security checks and integrate it with Amazon CodeGuru Reviewer to analyze and detect potential security vulnerabilities in the code before deploying it.

Amazon CodeGuru Reviewer helps you improve code security and provides recommendations based on common vulnerabilities (OWASP Top 10) and AWS security best practices. CodeGuru analyzes Java and Python code and provides recommendations for remediation. CodeGuru Reviewer detects a deviation from best practices when using AWS APIs and SDKs, and also identifies concurrency issues, resource leaks, security vulnerabilities and validates input parameters. For every workflow run, CodeGuru Reviewer’s GitHub Action copies your code and build artifacts into an S3 bucket and calls CodeGuru Reviewer APIs to analyze the artifacts and provide recommendations. Refer to the code detector library here for more information about CodeGuru Reviewer’s security and code quality detectors.

With GitHub Actions, developers can easily integrate CodeGuru Reviewer into their CI workflows, conducting code quality and security analysis. They can view CodeGuru Reviewer recommendations directly within the GitHub user interface to quickly identify and fix code issues and security vulnerabilities. Any pull request or push to the master branch will trigger a scan of the changed lines of code, and scheduled pipeline runs will trigger a full scan of the entire repository, ensuring comprehensive analysis and continuous improvement.

Solution overview

The solution comprises of the following components:

  1. GitHub Actions – Workflow Orchestration tool that will host the Pipeline.
  2. AWS CodeDeploy – AWS service to manage deployment on Amazon EC2 Autoscaling Group.
  3. AWS Auto Scaling – AWS service to help maintain application availability and elasticity by automatically adding or removing Amazon EC2 instances.
  4. Amazon EC2 – Destination Compute server for the application deployment.
  5. Amazon CodeGuru – AWS Service to detect security vulnerabilities and automate code reviews.
  6. AWS CloudFormation – AWS infrastructure as code (IaC) service used to orchestrate the infrastructure creation on AWS.
  7. AWS Identity and Access Management (IAM) OIDC identity provider – Federated authentication service to establish trust between GitHub and AWS to allow GitHub Actions to deploy on AWS without maintaining AWS Secrets and credentials.
  8. Amazon Simple Storage Service (Amazon S3) – Amazon S3 to store deployment and code scan artifacts.

The following diagram illustrates the architecture:

Figure 1. Architecture Diagram of the proposed solution in the blog.

Figure 1. Architecture Diagram of the proposed solution in the blog

  1. Developer commits code changes from their local repository to the GitHub repository. In this post, the GitHub action is triggered manually, but this can be automated.
  2. GitHub action triggers the build stage.
  3. GitHub’s Open ID Connector (OIDC) uses the tokens to authenticate to AWS and access resources.
  4. GitHub action uploads the deployment artifacts to Amazon S3.
  5. GitHub action invokes Amazon CodeGuru.
  6. The source code gets uploaded into an S3 bucket when the CodeGuru scan starts.
  7. GitHub action invokes CodeDeploy.
  8. CodeDeploy triggers the deployment to Amazon EC2 instances in an Autoscaling group.
  9. CodeDeploy downloads the artifacts from Amazon S3 and deploys to Amazon EC2 instances.

Prerequisites

This blog post is a continuation of our previous post – Integrating with GitHub Actions – CI/CD pipeline to deploy a Web App to Amazon EC2. You will need to setup your pipeline by following instructions in that blog.

After completing the steps, you should have a local repository with the below directory structure, and one completed Actions run.

Figure 2. Directory structure

Figure 2. Directory structure

To enable automated deployment upon git push, you will need to make a change to your .github/workflow/deploy.yml file. Specifically, you can activate the automation by modifying the following line of code in the deploy.yml file:

From:

workflow_dispatch: {}

To:

  #workflow_dispatch: {}
  push:
    branches: [ main ]
  pull_request:

Solution walkthrough

The following steps provide a high-level overview of the walkthrough:

  1. Create an S3 bucket for the Amazon CodeGuru Reviewer.
  2. Update the IAM role to include permissions for Amazon CodeGuru.
  3. Associate the repository in Amazon CodeGuru.
  4. Add Vulnerable code.
  5. Update GitHub Actions Job to run the Amazon CodeGuru Scan.
  6. Push the code to the repository.
  7. Verify the pipeline.
  8. Check the Amazon CodeGuru recommendations in the GitHub user interface.

1. Create an S3 bucket for the Amazon CodeGuru Reviewer

    • When you run a CodeGuru scan, your code is first uploaded to an S3 bucket in your AWS account.

Note that CodeGuru Reviewer expects the S3 bucket name to begin with codeguru-reviewer-.

    • You can create this bucket using the bucket policy outlined in this CloudFormation template (JSON or YAML) or by following these instructions.

2.  Update the IAM role to add permissions for Amazon CodeGuru

  • Locate the role created in the pre-requisite section, named “CodeDeployRoleforGitHub”.
  • Next, create an inline policy by following these steps. Give it a name, such as “codegurupolicy” and add the following permissions to the policy.
{
    “Version”: “2012-10-17",
    “Statement”: [
        {
            “Action”: [
                “codeguru-reviewer:ListRepositoryAssociations”,
                “codeguru-reviewer:AssociateRepository”,
                “codeguru-reviewer:DescribeRepositoryAssociation”,
                “codeguru-reviewer:CreateCodeReview”,
                “codeguru-reviewer:DescribeCodeReview”,
                “codeguru-reviewer:ListRecommendations”,
                “iam:CreateServiceLinkedRole”
            ],
            “Resource”: “*”,
            “Effect”: “Allow”
        },
        {
            “Action”: [
                “s3:CreateBucket”,
                “s3:GetBucket*“,
                “s3:List*“,
                “s3:GetObject”,
                “s3:PutObject”,
                “s3:DeleteObject”
            ],
            “Resource”: [
                “arn:aws:s3:::codeguru-reviewer-*“,
                “arn:aws:s3:::codeguru-reviewer-*/*”
            ],
            “Effect”: “Allow”
        }
    ]
}

3.  Associate the repository in Amazon CodeGuru

Figure 3. associate the repository

Figure 3. Associate the repository

At this point, you will have completed your initial full analysis run. However, since this is a simple “helloWorld” program, you may not receive any recommendations. In the following steps, you will incorporate vulnerable code and trigger the analysis again, allowing CodeGuru to identify and provide recommendations for potential issues.

4.  Add Vulnerable code

  • Create a file application.conf
    at /aws-codedeploy-github-actions-deployment/spring-boot-hello-world-example
  • Add the following content in application.conf file.
db.default.url="postgres://test-ojxarsxivjuyjc:ubKveYbvNjQ5a0CU8vK4YoVIhl@ec2-54-225-223-40.compute-1.amazonaws.com:5432/dcectn1pto16vi?ssl=true&sslfactory=org.postgresql.ssl.NonValidatingFactory"

db.default.url=${?DATABASE_URL}

db.default.port="3000"

db.default.datasource.username="root"

db.default.datasource.password="testsk_live_454kjkj4545FD3434Srere7878"

db.default.jpa.generate-ddl="true"

db.default.jpa.hibernate.ddl-auto="create"

5. Update GitHub Actions Job to run Amazon CodeGuru Scan

  • You will need to add a new job definition in the GitHub Actions’ yaml file. This new section should be inserted between the Build and Deploy sections for optimal workflow.
  • Additionally, you will need to adjust the dependency in the deploy section to reflect the new flow: Build -> CodeScan -> Deploy.
  • Review sample GitHub actions code for running security scan on Amazon CodeGuru Reviewer.
codescan:
    needs: build
    runs-on: ubuntu-latest
    permissions:
      id-token: write
      contents: read
      security-events: write

    steps:
    
    - name: Download an artifact
      uses: actions/download-artifact@v2
      with:
          name: build-file 
    
    - name: Configure AWS credentials
      id: iam-role
      continue-on-error: true
      uses: aws-actions/configure-aws-credentials@v1
      with:
          role-to-assume: ${{ secrets.IAMROLE_GITHUB }}
          role-session-name: GitHub-Action-Role
          aws-region: ${{ env.AWS_REGION }}
    
    - uses: actions/checkout@v2
      if: steps.iam-role.outcome == 'success'
      with:
        fetch-depth: 0 

    - name: CodeGuru Reviewer
      uses: aws-actions/[email protected]
      if: ${{ always() }} 
      continue-on-error: false
      with:          
        s3_bucket: ${{ env.S3bucket_CodeGuru }} 
        build_path: .

    - name: Store SARIF file
      if: steps.iam-role.outcome == 'success'
      uses: actions/upload-artifact@v2
      with:
        name: SARIF_recommendations
        path: ./codeguru-results.sarif.json

    - name: Upload review result
      uses: github/codeql-action/upload-sarif@v2
      with:
        sarif_file: codeguru-results.sarif.json
    

    - run: |
          
          echo "Check for critical volnurability"
          count=$(cat codeguru-results.sarif.json | jq '.runs[].results[] | select(.level == "error") | .level' | wc -l)
          if (( $count > 0 )); then
            echo "There are $count critical findings, hence stopping the pipeline."
            exit 1
          fi
  • Refer to the complete file provided below for your reference. It is important to note that you will need to replace the following environment variables with your specific values.
    • S3bucket_CodeGuru
    • AWS_REGION
    • S3BUCKET
name: Build and Deploy

on:
    #workflow_dispatch: {}
  push:
    branches: [ main ]
  pull_request:

env:
  applicationfolder: spring-boot-hello-world-example
  AWS_REGION: us-east-1 # <replace this with your AWS region>
  S3BUCKET: *<Replace your bucket name here>*
  S3bucket_CodeGuru: codeguru-reviewer-<*replacebucketnameher*> # S3 Bucket with "codeguru-reviewer-*" prefix


jobs:
  build:
    name: Build and Package
    runs-on: ubuntu-latest
    permissions:
      id-token: write
      contents: read
    steps:
      - uses: actions/checkout@v2
        name: Checkout Repository

      - uses: aws-actions/configure-aws-credentials@v1
        with:
          role-to-assume: ${{ secrets.IAMROLE_GITHUB }}
          role-session-name: GitHub-Action-Role
          aws-region: ${{ env.AWS_REGION }}

      - name: Set up JDK 1.8
        uses: actions/setup-java@v1
        with:
          java-version: 1.8

      - name: chmod
        run: chmod -R +x ./.github

      - name: Build and Package Maven
        id: package
        working-directory: ${{ env.applicationfolder }}
        run: $GITHUB_WORKSPACE/.github/scripts/build.sh

      - name: Upload Artifact to s3
        working-directory: ${{ env.applicationfolder }}/target
        run: aws s3 cp *.war s3://${{ env.S3BUCKET }}/
      
      - name: Artifacts for codescan action
        uses: actions/upload-artifact@v2
        with:
          name: build-file
          path: ${{ env.applicationfolder }}/target/*.war           

  codescan:
    needs: build
    runs-on: ubuntu-latest
    permissions:
      id-token: write
      contents: read
      security-events: write

    steps:
    
    - name: Download an artifact
      uses: actions/download-artifact@v2
      with:
          name: build-file 
    
    - name: Configure AWS credentials
      id: iam-role
      continue-on-error: true
      uses: aws-actions/configure-aws-credentials@v1
      with:
          role-to-assume: ${{ secrets.IAMROLE_GITHUB }}
          role-session-name: GitHub-Action-Role
          aws-region: ${{ env.AWS_REGION }}
    
    - uses: actions/checkout@v2
      if: steps.iam-role.outcome == 'success'
      with:
        fetch-depth: 0 

    - name: CodeGuru Reviewer
      uses: aws-actions/[email protected]
      if: ${{ always() }} 
      continue-on-error: false
      with:          
        s3_bucket: ${{ env.S3bucket_CodeGuru }} 
        build_path: .

    - name: Store SARIF file
      if: steps.iam-role.outcome == 'success'
      uses: actions/upload-artifact@v2
      with:
        name: SARIF_recommendations
        path: ./codeguru-results.sarif.json

    - name: Upload review result
      uses: github/codeql-action/upload-sarif@v2
      with:
        sarif_file: codeguru-results.sarif.json
    

    - run: |
          
          echo "Check for critical volnurability"
          count=$(cat codeguru-results.sarif.json | jq '.runs[].results[] | select(.level == "error") | .level' | wc -l)
          if (( $count > 0 )); then
            echo "There are $count critical findings, hence stopping the pipeline."
            exit 1
          fi
  deploy:
    needs: codescan
    runs-on: ubuntu-latest
    environment: Dev
    permissions:
      id-token: write
      contents: read
    steps:
    - uses: actions/checkout@v2
    - uses: aws-actions/configure-aws-credentials@v1
      with:
        role-to-assume: ${{ secrets.IAMROLE_GITHUB }}
        role-session-name: GitHub-Action-Role
        aws-region: ${{ env.AWS_REGION }}
    - run: |
        echo "Deploying branch ${{ env.GITHUB_REF }} to ${{ github.event.inputs.environment }}"
        commit_hash=`git rev-parse HEAD`
        aws deploy create-deployment --application-name CodeDeployAppNameWithASG --deployment-group-name CodeDeployGroupName --github-location repository=$GITHUB_REPOSITORY,commitId=$commit_hash --ignore-application-stop-failures

6.  Push the code to the repository:

  • Remember to save all the files that you have modified.
  • To ensure that you are in your git repository folder, you can run the command:
git remote -v
  • The command should return the remote branch address, which should be similar to the following:
username@3c22fb075f8a GitActionsDeploytoAWS % git remote -v
 origin	[email protected]:<username>/GitActionsDeploytoAWS.git (fetch)
 origin	[email protected]:<username>/GitActionsDeploytoAWS.git (push)
  • To push your code to the remote branch, run the following commands:

git add . 
git commit -m “Adding Security Scan” 
git push

Your code has been pushed to the repository and will trigger the workflow as per the configuration in GitHub Actions.

7.  Verify the pipeline

  • Your pipeline is set up to fail upon the detection of a critical vulnerability. You can also suppress recommendations from CodeGuru Reviewer if you think it is not relevant for setup. In this example, as there are two critical vulnerabilities, the pipeline will not proceed to the next step.
  • To view the status of the pipeline, navigate to the Actions tab on your GitHub console. You can refer to the following image for guidance.
Figure 4. github actions pipeline

Figure 4. GitHub Actions pipeline

  • To view the details of the error, you can expand the “codescan” job in the GitHub Actions console. This will provide you with more information about the specific vulnerabilities that caused the pipeline to fail and help you to address them accordingly.
Figure 5. Codescan actions logs

Figure 5. Codescan actions logs

8. Check the Amazon CodeGuru recommendations in the GitHub user interface

Once you have run the CodeGuru Reviewer Action, any security findings and recommendations will be displayed on the Security tab within the GitHub user interface. This will provide you with a clear and convenient way to view and address any issues that were identified during the analysis.

Figure 6. security tab with results

Figure 6. Security tab with results

Clean up

To avoid incurring future charges, you should clean up the resources that you created.

  1. Empty the Amazon S3 bucket.
  2. Delete the CloudFormation stack (CodeDeployStack) from the AWS console.
  3. Delete codeguru Amazon S3 bucket.
  4. Disassociate the GitHub repository in CodeGuru Reviewer.
  5. Delete the GitHub Secret (‘IAMROLE_GITHUB’)
    1. Go to the repository settings on GitHub Page.
    2. Select Secrets under Actions.
    3. Select IAMROLE_GITHUB, and delete it.

Conclusion

Amazon CodeGuru is a valuable tool for software development teams looking to improve the quality and efficiency of their code. With its advanced AI capabilities, CodeGuru automates the manual parts of code review and helps identify performance, cost, security, and maintainability issues. CodeGuru also integrates with popular development tools and provides customizable recommendations, making it easy to use within existing workflows. By using Amazon CodeGuru, teams can improve code quality, increase development speed, lower costs, and enhance security, ultimately leading to better software and a more successful overall development process.

In this post, we explained how to integrate Amazon CodeGuru Reviewer into your code build pipeline using GitHub actions. This integration serves as a quality gate by performing code analysis and identifying challenges in your code. Now you can access the CodeGuru Reviewer recommendations directly within the GitHub user interface for guidance on resolving identified issues.

About the author:

Mahesh Biradar

Mahesh Biradar is a Solutions Architect at AWS. He is a DevOps enthusiast and enjoys helping customers implement cost-effective architectures that scale.

Suresh Moolya

Suresh Moolya is a Senior Cloud Application Architect with Amazon Web Services. He works with customers to architect, design, and automate business software at scale on AWS cloud.

Shikhar Mishra

Shikhar is a Solutions Architect at Amazon Web Services. He is a cloud security enthusiast and enjoys helping customers design secure, reliable, and cost-effective solutions on AWS.