In the post Introducing the AWS ProServe Hadoop Migration Delivery Kit TCO tool, we introduced the AWS ProServe Hadoop Migration Delivery Kit (HMDK) TCO tool and the benefits of migrating on-premises Hadoop workloads to Amazon EMR. In this post, we dive deep into the tool, walking through all steps from log ingestion, transformation, visualization, and architecture design to calculate TCO.
Solution overview
Let’s briefly visit the HMDK TCO tool’s key features. The tool provides a YARN log collector to connect Hadoop Resource Manager to collect YARN logs. A Python-based Hadoop workload analyzer, called the YARN log analyzer, scrutinizes Hadoop applications. Amazon QuickSight dashboards showcase the results from the analyzer. The same results also accelerate the design of future EMR instances. Additionally, a TCO calculator generates the TCO estimation of an optimized EMR cluster for facilitating the migration.
Now let’s look at how the tool works. The following diagram illustrates the end-to-end workflow.
In the next sections, we walk through the five main steps of the tool:
Collect YARN job history logs.
Transform the job history logs from JSON to CSV.
Analyze the job history logs.
Design an EMR cluster for migration.
Calculate the TCO.
Prerequisites
Before getting started, make sure to complete the following prerequisites:
First, you run a YARN log collector, start-collector.sh, on your local machine. This step collects Hadoop YARN logs and places the logs on your local machine. The script connects your local machine with the Hadoop primary node and communicates with Resource Manager. Then it retrieves the job history information (YARN logs from application managers) by calling the YARN ResourceManager application API.
Prior to running the YARN log collector, you need to configure and establish the connection (HTTP: 8088 or HTTPS: 8090; the latter is recommended) to verify the accessibility of YARN ResourceManager and enabled YARN Timeline Server (Timeline Server v1 or later are supported). You may need to define the YARN logs’ collection interval and retention policy. To ensure that you collect consecutive YARN logs, you can use a cron job to schedule the log collector in a proper time interval. For example, for a Hadoop cluster with 2,000 daily applications and the setting yarn.resourcemanager.max-completed-applications set to 1,000, theoretically, you have to run the log collector at least twice to get all the YARN logs. In addition, we recommend collecting at least 7 days of YARN logs for analyzing holistic workloads.
Transform the YARN job history logs from JSON to CSV
After obtaining YARN logs, you run a YARN log organizer, yarn-log-organizer.py, which is a parser to transform JSON-based logs to CSV files. These output CSV files are the inputs for the YARN log analyzer. The parser also has other capabilities, including sorting events by time, removing dedicates, and merging multiple logs.
Next, you launch the YARN log analyzer to analyze the YARN logs in CSV format.
With QuickSight, you can visualize YARN log data and conduct analysis against the datasets generated by pre-built dashboard templates and a widget. The widget automatically creates QuickSight dashboards in the target AWS account, which configured in a CloudFormation template.
The following diagram illustrates the HMDK TCO architecture.
The YARN log analyzer provides four key functionalities:
Upload transformed YARN job history logs in CSV format (for example, cluster_yarn_logs_*.csv) to Amazon Simple Storage Service (Amazon S3) buckets. These CSV files are the outputs from the YARN log organizer.
Create a manifest JSON file (for example, yarn-log-manifest.json) for QuickSight and upload it to the S3 bucket:
Deploy QuickSight dashboards using a CloudFormation template, which is in YAML format. After deploying, choose the refresh icon until you see the stack’s status as CREATE_COMPLETE. This step creates datasets on QuickSight dashboards in your AWS target account.
On the QuickSight dashboard, you can find insights of the analyzed Hadoop workloads from various charts. These insights help you design future EMR instances for migration acceleration, as demonstrated in the next step.
Design an EMR cluster for migration
The results of the YARN log analyzer help you understand the actual Hadoop workloads on the existing system. This step accelerates designing future EMR instances for migration by using an Excel template. The template contains a checklist for conducting workload analysis and capacity planning:
Are the applications running on the cluster being used appropriately with their current capacity?
Is the cluster under load at a certain time or not? If so, when is the time?
What types of applications and engines (such as MR, TEZ, or Spark) are running on the cluster, and what is the resource usage for each type?
Are different jobs’ run cycles (real-time, batch, ad hoc) running in one cluster?
Are any jobs running in regular batches, and if so, what are these schedule intervals? (For example, every 10 minutes, 1 hour, 1 day.) Do you have jobs that use a lot of resources during a long time period?
Do any jobs need performance improvement?
Are any specific organizations or individuals monopolizing the cluster?
Are any mixed development and operation jobs operating in one cluster?
After you complete the checklist, you’ll have a better understanding of how to design the future architecture. For optimizing EMR cluster cost effectiveness, the following table provides general guidelines of choosing the proper type of EMR cluster and Amazon Elastic Compute Cloud (Amazon EC2) family.
To choose the proper cluster type and instance family, you need to perform several rounds of analysis against YARN logs based on various criteria. Let’s look at some key metrics.
Timeline
You can find workload patterns based on the number of Hadoop applications run in a time window. For example, the daily or hourly charts “Count of Records by Startedtime” provide the following insights:
In daily time series charts, you compare the number of application runs between working days and holidays, and among calendar days. If the numbers are similar, it means the daily utilizations of the cluster are comparable. On the other hand, if the deviation is large, the proportion of ad hoc jobs is significant. You also can figure out the possible weekly or monthly jobs on particular days. In the situation, you can easily see specific days in a week or a month with high workload concentration.
In hourly time series charts, you further understand how applications are run in hourly windows. You can find peak and off-peak hours in a day.
Users
The YARN logs contain the user ID of each application. This information helps you understand who submits an application to a queue. Based on the statistics of individual and aggregated application runs per queue and per user, you can determine the existing workload distribution by user. Usually, users at the same team have shared queues. Sometime, multiple teams have shared queues. When designing queues for users, you now have insights to help you design and distribute application workloads that are more balanced across queues than they previously were.
Application types
You can segment workloads based on various application types (such as Hive, Spark, Presto, or HBase) and run engines (such as MR, Spark, or Tez). For the compute-heavy workloads such as MapReduce or Hive-on-MR jobs, use CPU-optimized instances. For memory-intensive workloads such as Hive-on-TEZ, Presto, and Spark jobs, use memory-optimized instances.
ElapsedTime
You can categorize applications by runtime. The embedded CloudFormation template automatically creates an elapsedGroup field in a QuickSight dashboard. This enables a key feature to allow you to observe long-running jobs in one of four charts on QuickSight dashboards. Therefore, you can design tailored future architectures for these large jobs.
The corresponding QuickSight dashboards include four charts. You can drill down each chart, which is associated to one group.
Group Number
Runtime/Elapsed Time of a Job
1
Less than 10 minutes
2
Between 10 minutes and 30 minutes
3
between 30 minutes and 1 hour
4
Greater than 1 hour
In the chart of Group 4, you can concentrate on scrutinizing large jobs based on various metrics, including user, queue, application type, timeline, resource usage, and so on. Based on this consideration, you may have dedicated queues on a cluster or a dedicated EMR cluster for large jobs. Meanwhile, you may submit small jobs to shared queues.
Resources
Based on resource (CPU, memory) consumption patterns, you choose the right size and family of EC2 instances for performance and cost effectiveness. For compute-intensive applications, we recommend instances of CPU-optimized families. For memory-intensive applications, the memory-optimized instance families are recommended.
In addition, based on the nature of the application workloads and resource utilization over the time, you may choose a persistent or transient EMR cluster, Amazon EMR on EKS, or Amazon EMR Serverless.
After analyzing YARN logs by various metrics, you’re ready to design future EMR architectures. The following table lists examples of proposed EMR clusters. You can find more details in the optimized-tco-calculator GitHub repo.
Calculate TCO
Finally, on your local machine, run tco-input-generator.py to aggregate YARN job history logs on an hourly basis prior to using an Excel template to calculate the optimized TCO. This step is crucial because the results simulate the Hadoop workloads in future EMR instances.
The prerequisite of TCO simulation is to run tco-input-generator.py, which generates hourly aggregated logs. Next, you open an Excel template file to enable macros and provide your inputs in green cells for calculating the TCO. Regarding the input data, you enter the actual data size without replication, and the hardware specifications (vCore, mem) of the Hadoop primary node and data nodes. You also need to select and upload previously generated hourly aggregated logs. After you set the TCO simulation variables, such as Region, EC2 type, Amazon EMR high availability, engine effect, Amazon EC2 and Amazon EBS discount (EDP), Amazon S3 volume discount, local currency rate, and EMR EC2 task/core pricing ratio and price/hour, the TCO simulator automatically calculates the optimum cost of future EMR instances on Amazon EC2. The following screenshots show an example of HMDK TCO results.
After you complete all the steps and finish testing, complete the following steps to delete resources to avoid incurring costs:
On the AWS CloudFormation console, choose the stack you created.
Choose Delete.
Choose Delete stack.
Refresh the page until you see the status DELETE_COMPLETE.
On the Amazon S3 console, delete S3 bucket you created.
Conclusion
The AWS ProServe HMDK TCO tool significantly reduces migration planning efforts, which are the time-consuming and challenging tasks of assessing your Hadoop workloads. With the HMDK TCO tool, the assessment usually takes 2–3 weeks. You can also determine the calculated TCO of future EMR architectures. With the HMDK TCO tool, you are able to quickly understand your workloads and resource usage patterns. With the insights generated by the tool, you are equipped to design optimal future EMR architectures. In many use cases, a 1-year TCO of the optimized refactored architecture provides significant cost savings (64–80% reduction) on compute and storage, compared to lift-and-shift Hadoop migrations.
Sungyoul Park is a Senior Practice Manager at AWS ProServe. He helps customers innovate their business with AWS Analytics, IoT, and AI/ML services. He has a specialty in big data services and technologies and an interest in building customer business outcomes together.
Jiseong Kim is a Senior Data Architect at AWS ProServe. He mainly works with enterprise customers to help data lake migration and modernization, and provides guidance and technical assistance on big data projects such as Hadoop, Spark, data warehousing, real-time data processing, and large-scale machine learning. He also understands how to apply technologies to solve big data problems and build a well-designed data architecture.
George Zhao is a Senior Data Architect at AWS ProServe. He is an experienced analytics leader working with AWS customers to deliver modern data solutions. He is also a ProServe Amazon EMR domain specialist who enables ProServe consultants on best practices and delivery kits for Hadoop to Amazon EMR migrations. His area of interests are data lakes and cloud modern data architecture delivery.
Kalen Zhang was the Global Segment Tech Lead of Partner Data and Analytics at AWS. As a trusted advisor of data and analytics, she curated strategic initiatives for data transformation, led data and analytics workload migration and modernization programs, and accelerated customer migration journeys with partners at scale. She specializes in distributed systems, enterprise data management, advanced analytics, and large-scale strategic initiatives.
When migrating Hadoop workloads to Amazon EMR, it’s often difficult to identify the optimal cluster configuration without analyzing existing workloads by hand. To solve this, we’re introducing the Hadoop migration assessment Total Cost of Ownership (TCO) tool. You now have a Hadoop migration assessment TCO tool within the AWS ProServe Hadoop Migration Delivery Kit (HMDK). The self-serve HMDK TCO tool accelerates the design of new cost-effective Amazon EMR clusters by analyzing the existing Hadoop workload and calculating the total cost of the ownership (TCO) running on the future Amazon EMR system. The Amazon EMR TCO report with the new Amazon EMR design can demonstrate the Amazon EMR migration with detailed cost saving and business benefits.
In this post, we introduce a use case and the functions and components of the tool. We also share case studies to show you the benefits of using the tool. Finally, we show you the technical information to use the tool.
Use case overview
Migrating Hadoop workloads to Amazon EMR accelerates big data analytics modernization, increases productivity, and reduces operational cost. Refactoring coupled compute and storage to a decoupling architecture is a modern data solution. It enables compute such as EMR instances and storage such as Amazon Simple Storage Service (Amazon S3) data lakes to scale. For various Hadoop jobs, customers have bespoke deployment options of fully managed Amazon EMR, Amazon EMR on Amazon EKS, and EMR Serverless. The optimized future EMR cluster yields the same results and values with much lower TCO compared to the source Hadoop cluster. But we need a TCO report to showcase the cost saving details, as shown in the following figure.
Typically, the commencement of a Hadoop migration needs Hadoop experts to spend weeks or even months to assess current Hadoop cluster workloads towards a plan for subsequent migration. This could delay the project from being accepted without a good TCO report.
To accelerate Hadoop migrations and mitigate the workload assessment efforts by SMEs, AWS ProServe created the Hadoop migration assessment TCO tool within the AWS ProServe Hadoop Migration Delivery Kit.
Introduction to the HMDK TCO tool
As a Hadoop migration accelerator, the HMDK TCO tool has three components:
YARN log collector – Retrieves the existing workload logs from YARN Resource Manager
YARN log analyzer – Provides a deep time-based insight on different aspects of the jobs
TCO calculator – Generates a 3-year or 1-year TCO calculated automatically
The self-serve HMDK TCO tool is available for download on GitHub.
Using the tool consists of three steps:
First, the YARN Log collector communicates with the current Hadoop system to retrieve YARN logs.
With the collected YARN logs, the next step is to use the YARN log analyzer and set up the log analyzer stack using AWS CloudFormation. The results of the log analyzer reveal Hadoop workload insights with various views and metrics of the Hadoop applications shown in Amazon QuickSight dashboards, which leads to the design of a future EMR cluster.
Lastly, the TCO calculator generates the TCO report by simulating hourly resource usage of a future EMR cluster. To accelerate Hadoop migration assessment, the TCO report provides crucial information and values for your business stakeholders to make a buy-in decision.
The following diagram illustrates this architecture.
The Hadoop workload insights enable you to design a well-architected EMR cluster to achieve performance and cost-effectiveness in an agile way. For conducting well-architected designs, you need to deliberate between various system specifications of an EMR cluster and multiple cost considerations.
The system specifications are as follows:
Number of EMR clusters – Amazon EMR enables you to run multiple elastic clusters in the AWS Cloud to serve the same purpose of a shared static Hadoop cluster on premises
Types of EMR cluster (persistent or transient) – Design your system to keep minimum persistent clusters to save cost
Instance types and configuration (memory, vCore, and so on) – Choose the right instance for your job
Resource allocation for applications and cluster utilization – Based on the on-premises workload analysis, design effective resource allocation and efficient resource utilization in future EMR clusters
The cost considerations are as follows:
Latest price list (from thousands of available EC2 instances available) – The HMDK TCO tool makes the price calculation with Amazon Elastic Compute Cloud (Amazon EC2) instance types, configurations, and their prices.
Amazon S3 storage cost (standard, Glacier, and so on) – Data replication is no longer required for reliability. You can use tired storage in Amazon S3 for cost savings.
YARN log collector
The HMDK TCO tool enables a simple way to capture Hadoop YARN logs, which include the Hadoop job runs statistics and the corresponding resource usages. The following screenshot is an example of a YARN log.
The tool supports HTTPS protocol to communicate with YARN Resource Manager. The tool transports the JSON YARN logs as the inputs to a Python parser, which converts the YARN logs from JSON to CSV format. The new CSV formatted logs are the standard input files for the YARN log analyzer.
With the log, we can follow up the steps in the TCO yarn-log-analysis README file to use AWS CloudFormation to set up QuickSight resources.
The HMDK TCO log analyzer generates a QuickSight dashboard on various metrics:
Job timeline – How many jobs are running at one time
Job user – Breakdown of users and queues
Application type and engine type – Breakdown by application types (Spark, Hive, Presto) and run engine type (MapReduce, Spark, Tez)
Elapsed time – The time span of completing an application
Resources – Memory and CPU
The following screenshot shows an example dashboard.
The QuickSight dashboards exhibit insights based on consecutive YARN logs collected in a long-enough period of time (for example, a 2-week window). The insights from the logs reveal the application types, users, queues, running cadence, time spans, and resource usages. The data also helps you discover daily batch jobs or ad hoc jobs, long-running jobs, and resource consumption. These insights help you design the right clusters, such as transient clusters or baseline permanent clusters, and choose the right EC2 instance for memory- or compute-intensive jobs. With the log analyzer results, the TCO tool automatically calculates the TCO of a future EMR cluster.
Let’s see some real customer use cases in the following sections.
Case 1: Use transient and persistent clusters wisely
For this use case, a customer in the financial sector has an 11-node Hadoop cluster.
The QuickSight timeline dashboard shows the peak time job runs because of the daily batch job. This guides us to design two clusters for fulfilling the existing workloads. When we keep a persistent cluster at a minimal size, we can have the transient EMR cluster to handle the batch style job around the peak time.
Therefore, we designed the clusters to have a persistent cluster with 2 data nodes, while transient nodes can scale from 0–10 between the hours of 1:00 AM and 4:00 AM.
The following figure illustrates this design.
This balanced design using transient and persistent clusters resulted in a cost savings of about 80% compared to a lift-and-shift design.
Case 2: Identify Hadoop queue usage and long-running jobs to design multiple clusters and optimized runs
For our next use case, a company runs 196 nodes using Hadoop 3.1 with jobs like Hive, Spark, and Kafka. The Hadoop default queue and four other queues were used to group various workloads. As illustrated in the following figure, some very long-running jobs are seen in the shared cluster, resulting in queued jobs that have resource competition and unbalanced resource allocation.
The QuickSight user dashboard guides us through the queue usage, the elapsed time dashboard guides us through the long-running jobs, and the resource dashboard guides us through the memory and vCore usage for the jobs.
Therefore, we design a solution to transfer queue jobs to run in separated clusters, and the default queue jobs are split to run in different clusters. By identifying the long-running jobs and understanding the resource needs, we could design a cluster to run such jobs more efficiently.
This design allows the job to run faster and the clusters to be used more efficiently with a cost savings benefit.
Cluster design
The HMDK TCO tool provides a cluster design template like the following example.
Here we have two clusters, one transient and one persistent, to handle the Spark and Tez jobs accordingly. The starting and ending hour for each cluster can be determined from the log analysis. With this cluster design, we can get the hourly workload resource usage forecast. Then the TCO calculator gets all the information needed to generate costs based on the TCO simulation variables you choose.
TCO calculator
The HMDK TCO calculator is a component guiding the EMR cluster design by using the EMR design template. Then it generates the hourly aggregated resource usage forecast using a Python program. The component provides guidelines and an Excel template to input system and cost specification parameters. The component has the logic with a built-in Amazon EMR price list. The 1-year and 3-year TCO cost can be automatically generated by the macro-enabled Excel TCO template.
The following figure shows the details of our HMDK TCO simulation.
The following figures show the TCO report.
TCO tool engagement outcomes
In this section, we share some of the engagement outcomes from customers after using the TCO tool for 1–2 weeks. Additionally, with the TCO tool, we can refactor on-premises Hadoop clusters to EMR clusters utilizing Amazon S3 as a data lake. The modern data solution of migrating to Amazon EMR provides unlimited scalability with operational efficiency and cost savings.
The following table illustrates four case studies of some engagements using the tool.
Case#
Case Description
Engagement Outcome
1
Pressured by the Hadoop License, they migrated to AWS using Amazon EMR and used Spark for replacing Hive. They designed the new EMR clusters using a balanced design of transient and persistent clusters.
They can get job insights through the tool and design the new EMR clusters to fulfill the existing workloads, and expect to achieve 80% cost savings and six times performance enhancement.
2
Their goal was to migrate a Hadoop cluster with over 1,000 nodes from HDFS to Amazon S3 and Hive to Spark, and redesign the cluster using a balanced design of transient and persistent clusters.
They can get job insights and redesign the cluster with a 1-year TCO of the optimized redesign architecture expected to have 64% cost savings.
3
Their goal was to migrate to Hadoop 3.1. They transferred the Hadoop queue-based job, which shared the same cluster, to two transient clusters and five persistent clusters with optimized resource usage for each job run, and handled long-running jobs faster.
They can get Amazon EMR TCO results quickly in 2 weeks. Customers get insights on their workloads and long-running jobs and get the job done faster and cheaper.
4
Their goal was to migrate from Hive 1 to Spark and design an auto scaling EMR cluster.
They can get Amazon EMR TCO results in 1 week. They’re expecting to see 75% cost savings on the redesigned EMR clusters and 10 times on performance improvement.
Conclusion
This post introduced use cases, functions, and components of the HMDK TCO tool. Through the case studies discussed in this post, you learned about real examples of the tool usage and its benefits. The HMDK TCO tool is designed for automating source Hadoop cluster workload assessment with calculated TCO calculation, and it can be done in 2–3 weeks instead of months.
More and more customers are adopting the HMDK TCO tool to accelerate their migration to Amazon EMR.
Sungyoul Park is a Senior Practice Manager at AWS ProServe. He helps customers innovate their business with AWS Analytics, IoT, and AI/ML services. He has a specialty in big data services and technologies and an interest in building customer business outcomes together.
Jiseong Kim is a Senior Data Architect at AWS ProServe. He mainly works with enterprise customers to help data lake migration and modernization, and provides guidance and technical assistance on big data projects such as Hadoop, Spark, data warehousing, real-time data processing, and large-scale machine learning. He also understands how to apply technologies to solve big data problems and build a well-designed data architecture.
George Zhao is a Senior Data Architect at AWS ProServe. He is an experienced analytics leader working with AWS customers to deliver modern data solutions. He is also a ProServe Amazon EMR domain specialist who enables ProServe consultants on best practices and delivery kits for Hadoop to Amazon EMR migrations. His area of interests are data lakes and cloud modern data architecture delivery.
Kalen Zhang was the Global Segment Tech Lead of Partner Data and Analytics at AWS. As a trusted advisor of data and analytics, she curated strategic initiatives for data transformation, led data and analytics workload migration and modernization programs, and accelerated customer migration journeys with partners at scale. She specializes in distributed systems, enterprise data management, advanced analytics, and large-scale strategic initiatives.
Amazon Managed Workflows for Apache Airflow (Amazon MWAA) is a managed orchestration service for Apache Airflow that makes it simple to set up and operate end-to-end data pipelines in the cloud at scale. A data pipeline is a set of tasks and processes used to automate the movement and transformation of data between different systems. The Apache Airflow open-source community provides over 1,000 pre-built operators (plugins that simplify connections to services) for Apache Airflow to build data pipelines. The Amazon provider package for Apache Airflow comes with integrations for over 31 AWS services, such as Amazon Simple Storage Service (Amazon S3), Amazon Redshift, Amazon EMR, AWS Glue, Amazon SageMaker, and more.
The most common use case for Airflow is ETL (extract, transform, and load). Nearly all Airflow users implement ETL pipelines ranging from simple to complex. Operationalizing machine learning (ML) is another growing use case, where data has to be transformed and normalized before it can be loaded into an ML model. In both use cases, the data pipeline is preparing the data for consumption by ingesting data from different sources and transforming it through a series of steps.
Observability across the different processes within the data pipeline is a key component to monitor the success or failure of the pipeline. Although scheduling the runs of tasks within the data pipeline is controlled by Airflow, the run of the task itself (transforming, normalizing, and aggregating data) is done by different services based on the use case. Having an end-to-end view of the data flow is a challenge due to multiple touch points in the data pipeline.
In this post, we provide an overview of logging enhancements when working with Amazon MWAA, which is one of the pillars of observability. We then discuss a solution to further enhance end-to-end observability by modifying the task definitions that make up the data pipeline. For this post, we focus on task definitions for two services: AWS Glue and Amazon EMR, however the same method can be applied across different services.
Challenge
Many customers’ data pipelines start simple, orchestrating a few tasks, and over time grow to be more complex, consisting of a large number of tasks and dependencies between them. As the complexity increases, it becomes increasingly hard to operate and debug in case of failure, which creates a need for a single pane of glass to provide end-to-end data pipeline orchestration and health management. For data pipeline orchestration, the Apache Airflow UI is a user-friendly tool that provides detailed views into your data pipeline. When it comes to pipeline health management, each service that your tasks are interacting with could be storing or publishing logs to different locations, such as an S3 bucket or Amazon CloudWatch logs. As the number of integration touch points increases, stitching the distributed logs generated by different services in various locations can be challenging.
One solution provided by Amazon MWAA to consolidate the Airflow and task logs within the directed acyclic graph (DAG) is to forward the logs to CloudWatch log groups. A separate log group is created for each enabled Airflow logging option (For example, DAGProcessing, Scheduler, Task, WebServer, and Worker). These logs can be queried across log groups using CloudWatch Logs Insights.
A common approach in distributed tracing is to use a correlation ID to stitch and query distributed logs. A correlation ID is a unique identifier that is passed through a request flow for tracking a sequence of activities throughout the lifetime of the workflow. When each service in the workflow needs to log information, it can include this correlation ID, thereby ensuring you can track a full request from start to finish.
The Airflow engine passes a few variables by default that are accessible to all templates. run_id is one such variable, which is a unique identifier for a DAG run. The run_id can be used as the correlation ID to query against different log groups within CloudWatch to capture all the logs for a particular DAG run.
However, be aware that services that your tasks are interacting with will use a separate log group and won’t log the run_id as part of their output. This will prevent you from getting an end-to-end view across the DAG run.
For example, if your data pipeline consists of an AWS Glue task running a Spark job as part of the pipeline, then the Airflow task logs will be available in one CloudWatch log group and the AWS Glue job logs will be in a different CloudWatch log group. However, the Spark job that is run as part of the AWS Glue job doesn’t have access to the correlation ID and can’t be tied back to a particular DAG run. So even if you use the correlation ID to query the different CloudWatch log groups, you won’t get any information about the run of the Spark job.
Solution overview
As you now know, run_id is a variable that is a unique identifier for a DAG run. The run_id is present as part of the Airflow task logs. To use the run_id effectively and increase the observability across the DAG run, we use run_id as the correlation ID and pass it to different tasks with the DAG. The correlation ID is then be consumed by the scripts used within the tasks.
The following diagram illustrates the solution architecture.
The data pipeline that we focus on consists of the following components:
An S3 bucket that contains the source data
An AWS Glue crawler that creates the table metadata in the Data Catalog from the source data
An AWS Glue job that transforms the raw data into a processed data format while performing file format conversions
In this section, we look at snippets of the additions needed to the DAG file. We also discuss how to pass the correlation ID to the AWS Glue and EMR jobs. Refer to the GitHub repo for the complete DAG code.
Next, let’s look at how to pass the correlation ID to the AWS Glue job using the AWS Glue operator. Operators are the building blocks of Airflow DAGs. They contain the logic of how data is processed in the data pipeline. Each task in a DAG is defined by instantiating an operator.
Airflow provides operators for different tasks. For this post, we use the AWS Glue operator.
The AWS Glue task definition contains the following:
We pass the DAG name, task ID, and correlation ID as arguments to the steps for the EMR task.
Let’s start with defining the configuration for the EMR cluster. The correlation_id is passed in the name of the cluster to easily identify the cluster corresponding to a DAG run. The logs generated by EMR jobs are published to a S3 bucket; the correlation_id is part of the LogUri as well. See the following code:
Next, let’s define the steps needed to run as part of the EMR job. The input and output data processed by the EMR job is stored in an S3 bucket passed as arguments. Dag_name, task_id, and correlation_id are also passed in as arguments. The task_id used can be the name of your choice; here we use add_steps:
Next, let’s add a task to run the steps on the EMR cluster. The job_flow_id is the ID of the JobFlow, which is passed down from the EMR create task described earlier using Airflow XComs. See the following code:
This completes the steps needed to pass the correlation ID within the DAG task definition.
In the next section, we use this ID within the script run to log details.
Job script definitions
In this section, we review the changes required to log information based on the correlation_id. Let’s start with the AWS Glue job script (for the complete code, refer to the following file in GitHub):
This completes the steps for passing the correlation ID to the script run.
After we complete the DAG definitions and script additions, we can run the DAG. Logs for a particular DAG run can be queried using the correlation ID. The correlation ID for a DAG run can be found via the Airflow UI. An example of a correlation ID is manual__2022-07-12T00:22:36.111190+00:00. With this unique string, we can run queries on the relevant CloudWatch log groups using CloudWatch Logs Insights. The result of the query includes the logging provided by the AWS Glue and EMR scripts, along with other logs associated with the correlation ID.
Example query for DAG level logs : manual__2022-07-12T00:22:36.111190+00:00
We can also obtain task-level logs by using the format <dag_name.task_id correlation_id>:
Example query : data_pipeline.glue_task manual__2022-07-12T00:22:36.111190+00:00
Clean up
If you created the setup to run and test the scripts using the Amazon MWAA analytics workshop, perform the cleanup steps to avoid incurring charges.
Conclusion
In this post, we showed how to send Amazon MWAA logs to CloudWatch log groups. We then discussed how to tie in logs from different tasks within a DAG using the unique correlation ID. The correlation ID can be outputted with as much or as little information needed by your job to provide more details across your entire DAG run. You can then use CloudWatch Logs Insights to query the logs.
With this solution, you can use Amazon MWAA as a single pane of glass for data pipeline orchestration and CloudWatch logs for data pipeline health management. The unique identifier improves the end-to-end observability for a DAG run and helps reduce the time needed for troubleshooting.
To learn more and get hands-on experience, start with the Amazon MWAA analytics workshop and then use the scripts in the GitHub repo to gain more observability of your DAG run.
About the Author
Payal Singh is a Partner Solutions Architect at Amazon Web Services, focused on the Serverless platform. She is responsible for helping partner and customers modernize and migrate their applications to AWS.
Ransomware events have significantly increased over the past several years and captured worldwide attention. Traditional ransomware events affect mostly infrastructure resources like servers, databases, and connected file systems. However, there are also non-traditional events that you may not be as familiar with, such as ransomware events that target data stored in Amazon Simple Storage Service (Amazon S3). There are important steps you can take to help prevent these events, and to identify possible ransomware events early so that you can take action to recover. The goal of this post is to help you learn about the AWS services and features that you can use to protect against ransomware events in your environment, and to investigate possible ransomware events if they occur.
Ransomware is a type of malware that bad actors can use to extort money from entities. The actors can use a range of tactics to gain unauthorized access to their target’s data and systems, including but not limited to taking advantage of unpatched software flaws, misuse of weak credentials or previous unintended disclosure of credentials, and using social engineering. In a ransomware event, a legitimate entity’s access to their data and systems is restricted by the bad actors, and a ransom demand is made for the safe return of these digital assets. There are several methods actors use to restrict or disable authorized access to resources including a) encryption or deletion, b) modified access controls, and c) network-based Denial of Service (DoS) attacks. In some cases, after the target’s data access is restored by providing the encryption key or transferring the data back, bad actors who have a copy of the data demand a second ransom—promising not to retain the data in order to sell or publicly release it.
In the next sections, we’ll describe several important stages of your response to a ransomware event in Amazon S3, including detection, response, recovery, and protection.
After a bad actor has obtained credentials, they use AWS API actions that they iterate through to discover the type of access that the exposed IAM principal has been granted. Bad actors can do this in multiple ways, which can generate different levels of activity. This activity might alert your security teams because of an increase in API calls that result in errors. Other times, if a bad actor’s goal is to ransom S3 objects, then the API calls will be specific to Amazon S3. If access to Amazon S3 is permitted through the exposed IAM principal, then you might see an increase in API actions such as s3:ListBuckets, s3:GetBucketLocation, s3:GetBucketPolicy, and s3:GetBucketAcl.
Analysis
In this section, we’ll describe where to find the log and metric data to help you analyze this type of ransomware event in more detail.
When a ransomware event targets data stored in Amazon S3, often the objects stored in S3 buckets are deleted, without the bad actor making copies. This is more like a data destruction event than a ransomware event where objects are encrypted.
There are several logs that will capture this activity. You can enable AWS CloudTrail event logging for Amazon S3 data, which allows you to review the activity logs to understand read and delete actions that were taken on specific objects.
In addition, if you have enabled Amazon CloudWatch metrics for Amazon S3 prior to the ransomware event, you can use the sum of the BytesDownloaded metric to gain insight into abnormal transfer spikes.
Another way to gain information is to use the region-DataTransfer-Out-Bytes metric, which shows the amount of data transferred from Amazon S3 to the internet. This metric is enabled by default and is associated with your AWS billing and usage reports for Amazon S3.
Next, we’ll walk through how to respond to the unintended disclosure of IAM access keys. Based on the business impact, you may decide to create a second set of access keys to replace all legitimate use of those credentials so that legitimate systems are not interrupted when you deactivate the compromised access keys. You can deactivate the access keys by using the IAM console or through automation, as defined in your incident response plan. However, you also need to document specific details for the event within your secure and private incident response documentation so that you can reference them in the future. If the activity was related to the use of an IAM role or temporary credentials, you need to take an additional step and revoke any active sessions. To do this, in the IAM console, you choose the Revoke active session button, which will attach a policy that denies access to users who assumed the role before that moment. Then you can delete the exposed access keys.
In addition, you can use the AWS CloudTrail dashboard and event history (which includes 90 days of logs) to review the IAM related activities by that compromised IAM user or role. Your analysis can show potential persistent access that might have been created by the bad actor. In addition, you can use the IAM console to look at the IAM credential report (this report is updated every 4 hours) to review activity such as access key last used, user creation time, and password last used. Alternatively, you can use Amazon Athena to query the CloudTrail logs for the same information. See the following example of an Athena query that will take an IAM user Amazon Resource Number (ARN) to show activity for a particular time frame.
SELECT eventtime, eventname, awsregion, sourceipaddress, useragent
FROM cloudtrail
WHERE useridentity.arn = 'arn:aws:iam::1234567890:user/Name' AND
-- Enter timeframe
(event_date >= '2022/08/04' AND event_date <= '2022/11/04')
ORDER BY eventtime ASC
Recovery
After you’ve removed access from the bad actor, you have multiple options to recover data, which we discuss in the following sections. Keep in mind that there is currently no undelete capability for Amazon S3, and AWS does not have the ability to recover data after a delete operation. In addition, many of the recovery options require configuration upon bucket creation.
S3 Versioning
Using versioning in S3 buckets is a way to keep multiple versions of an object in the same bucket, which gives you the ability to restore a particular version during the recovery process. You can use the S3 Versioning feature to preserve, retrieve, and restore every version of every object stored in your buckets. With versioning, you can recover more easily from both unintended user actions and application failures. Versioning-enabled buckets can help you recover objects from accidental deletion or overwrite. For example, if you delete an object, Amazon S3 inserts a delete marker instead of removing the object permanently. The previous version remains in the bucket and becomes a noncurrent version. You can restore the previous version. Versioning is not enabled by default and incurs additional costs, because you are maintaining multiple copies of the same object. For more information about cost, see the Amazon S3 pricing page.
AWS Backup
Using AWS Backup gives you the ability to create and maintain separate copies of your S3 data under separate access credentials that can be used to restore data during a recovery process. AWS Backup provides centralized backup for several AWS services, so you can manage your backups in one location. AWS Backup for Amazon S3 provides you with two options: continuous backups, which allow you to restore to any point in time within the last 35 days; and periodic backups, which allow you to retain data for a specified duration, including indefinitely. For more information, see Using AWS Backup for Amazon S3.
Protection
In this section, we’ll describe some of the preventative security controls available in AWS.
S3 Object Lock
You can add another layer of protection against object changes and deletion by enabling S3 Object Lock for your S3 buckets. With S3 Object Lock, you can store objects using a write-once-read-many (WORM) model and can help prevent objects from being deleted or overwritten for a fixed amount of time or indefinitely.
AWS Backup Vault Lock
Similar to S3 Object lock, which adds additional protection to S3 objects, if you use AWS Backup you can consider enabling AWS Backup Vault Lock, which enforces the same WORM setting for all the backups you store and create in a backup vault. AWS Backup Vault Lock helps you to prevent inadvertent or malicious delete operations by the AWS account root user.
Amazon S3 Inventory
To make sure that your organization understands the sensitivity of the objects you store in Amazon S3, you should inventory your most critical and sensitive data across Amazon S3 and make sure that the appropriate bucket configuration is in place to protect and enable recovery of your data. You can use Amazon S3 Inventory to understand what objects are in your S3 buckets, and the existing configurations, including encryption status, replication status, and object lock information. You can use resource tags to label the classification and owner of the objects in Amazon S3, and take automated action and apply controls that match the sensitivity of the objects stored in a particular S3 bucket.
MFA delete
Another preventative control you can use is to enforce multi-factor authentication (MFA) delete in S3 Versioning. MFA delete provides added security and can help prevent accidental bucket deletions, by requiring the user who initiates the delete action to prove physical or virtual possession of an MFA device with an MFA code. This adds an extra layer of friction and security to the delete action.
Use IAM roles for short-term credentials
Because many ransomware events arise from unintended disclosure of static IAM access keys, AWS recommends that you use IAM roles that provide short-term credentials, rather than using long-term IAM access keys. This includes using identity federation for your developers who are accessing AWS, using IAM roles for system-to-system access, and using IAM Roles Anywhere for hybrid access. For most use cases, you shouldn’t need to use static keys or long-term access keys. Now is a good time to audit and work toward eliminating the use of these types of keys in your environment. Consider taking the following steps:
Create an inventory across all of your AWS accounts and identify the IAM user, when the credentials were last rotated and last used, and the attached policy.
Disable and delete all AWS account root access keys.
Rotate the credentials and apply MFA to the user.
Re-architect to take advantage of temporary role-based access, such as IAM roles or IAM Roles Anywhere.
Review attached policies to make sure that you’re enforcing least privilege access, including removing wild cards from the policy.
Server-side encryption with customer managed KMS keys
Another protection you can use is to implement server-side encryption with AWS Key Management Service (SSE-KMS) and use customer managed keys to encrypt your S3 objects. Using a customer managed key requires you to apply a specific key policy around who can encrypt and decrypt the data within your bucket, which provides an additional access control mechanism to protect your data. You can also centrally manage AWS KMS keys and audit their usage with an audit trail of when the key was used and by whom.
GuardDuty protections for Amazon S3
You can enable Amazon S3 protection in Amazon GuardDuty. With S3 protection, GuardDuty monitors object-level API operations to identify potential security risks for data in your S3 buckets. This includes findings related to anomalous API activity and unusual behavior related to your data in Amazon S3, and can help you identify a security event early on.
Conclusion
In this post, you learned about ransomware events that target data stored in Amazon S3. By taking proactive steps, you can identify potential ransomware events quickly, and you can put in place additional protections to help you reduce the risk of this type of security event in the future.
Since its launch in 2006, Amazon Simple Storage Service (Amazon S3) has experienced major growth, supporting multiple use cases such as hosting websites, creating data lakes, serving as object storage for consumer applications, storing logs, and archiving data. As the application portfolio grows, customers tend to store data from multiple application and different business functions in a single S3 bucket, which can grow the storage in S3 buckets to hundreds of TBs. The AWS Billing console provides a way to look at the total storage cost of data stored in Amazon S3, but sometimes IT organizations need to understand the breakdown of costs of a particular S3 bucket by various prefixes or objects corresponding to a particular user or application. There are various reasons to analyze the costs of S3 buckets, such as to identify the spend breakdown, do internal chargebacks, understand the cost breakdown by business unit and application, and many more. As of this writing, there is no easy way to do a cost breakdown of S3 buckets by objects and prefixes.
The following figure shows the architecture for this solution. First, we enable the AWS Cost and Usage Reports (AWS CUR) and Amazon S3 Inventory features, which save the output into two separate pre-created S3 buckets. We then use Athena to query these S3 buckets for AWS CUR data and S3 object inventory data to correlate and allocate the cost breakdown at the object or prefix level.
To implement the solution, we complete the following steps:
Create S3 buckets for AWS CUR, S3 object inventory, and Athena results. Alternatively, you can create these respective buckets when enabling the respective individual features, but for the purpose of this post, we create all of them at the beginning.
Enable the Cost and Usage Reports.
Enable Amazon S3 Inventory configuration.
Create AWS Glue Data Catalog tables for the CUR and S3 object inventory to query using Athena.
Run queries in Athena.
Prerequisites
For this walkthrough, you should have the following prerequisites:
Amazon S3 is an object storage service offering industry-leading scalability, data availability, security, and performance. Customers of all sizes and industries can store and protect any amount of data for virtually any use case, such as data lakes, cloud-native applications, and mobile apps. With cost-effective storage classes and easy-to-use management features, you can optimize costs, organize data, and configure fine-tuned access controls to meet specific business, organizational, and compliance requirements.
For this post, we use the S3 bucket s3-object-cost-allocation as the primary bucket for cost allocation. This S3 bucket is conveniently modeled to contain several prefixes and objects of different sizes for which cost allocation needs to be done based on the overall cost of the bucket. In a real-world scenario, you should use a bucket that has data for multiple teams and for which you need to allocate costs by prefix or object. Going forward, we refer to this bucket as the primary object bucket.
The following screenshot shows our S3 bucket and folders.
Now let’s create the three additional operational S3 buckets to store the datasets generated to calculate costs for the objects. You can create the following buckets or any existing buckets as needed:
cur-cost-usage-reports-<account_number> – This bucket is used to save the Cost and Usage Reports for the account.
S3-inventory-configurations-<account_number> – This bucket is used to save the inventory configurations of our primary object bucket.
athena-query-bucket-<account_number> – This bucket is used to save the query results from Athena.
Complete the following steps to create your S3 buckets:
On the Amazon S3 console, choose Buckets in the navigation pane.
Choose Create bucket.
For Bucket name, enter the name of your bucket (cur-cost-usage-reports-<account_number>).
For AWS Region, choose your preferred Region.
Leave all other settings at default (or according to your organization’s standards).
Choose Create bucket.
Repeat these steps to create s3-inventory-configurations-<account_number> and athena-query-bucket-<account_number>.
Enable the Cost and Usage Reports
The AWS Cost and Usage Reports (AWS CUR) contains the most comprehensive set of cost and usage data available. You can use Cost and Usage Reports to publish your AWS billing reports to an S3 bucket that you own. You can receive reports that break down your costs by the hour, day, or month; by product or product resource; or by tags that you define yourself.
Complete the following steps to enable Cost and Usage Reports for your account:
On the AWS Billing console, in the navigation pane, choose Cost & Usage Reports.
Choose Create report.
For Report name, enter a name for your report, such as account-cur-s3.
For Additional report details, select Include resource IDs to include the IDs of each individual resource in the report.Including resource IDs will create individual line items for each of your resources. This can increase the size of your Cost and Usage Reports files significantly, which can affect the S3 storage costs for your CUR, based on your AWS usage. We need this feature enabled for this post.
For Data refresh settings, select whether you want the Cost and Usage Reports to refresh if AWS applies refunds, credits, or support fees to your account after finalizing your bill.When a report refreshes, a new report is uploaded to Amazon S3.
Choose Next.
For S3 bucket, choose Configure.
For Configure S3 Bucket, select an existing bucket created in the previous section (cur-cost-usage-reports-<account_number>) and choose Next.
Review the bucket policy, select I have confirmed that this policy is correct, and choose Save. This default bucket policy provides Cost and Usage Reports access to write data to Amazon S3.
For Report path prefix, enter cur-data/account-cur-daily.
For Time granularity, choose Daily.
For Report versioning, choose Overwrite existing report.
For Enable report data integration for, select Amazon Athena.
Choose Next.
After you have reviewed the settings for your report, choose Review and Complete.
The Cost and Usage reports will be delivered to the S3 buckets within 24 hours.
The following sample CUR in CSV format shows different columns of the Cost and Usage Report, including bill_invoice_id, bill_invoicing_entity, bill_payer_account_id, and line_item_product_code, to name a few.
Enable Amazon S3 Inventory configuration
Amazon S3 Inventory is one of the tools Amazon S3 provides to help manage your storage. You can use it to audit and report on the replication and encryption status of your objects for business, compliance, and regulatory needs. Amazon S3 Inventory provides comma-separated values (CSV), Apache Optimized Row Columnar (ORC), or Apache Parquet output files that list your objects and their corresponding metadata on a daily or weekly basis for an S3 bucket or a shared prefix (objects that have names that begin with a common string).
Complete the following steps to enable Amazon S3 Inventory on the primary object bucket:
On the Amazon S3 console, choose Buckets in the navigation pane.
Choose the bucket for which you want to configure Amazon S3 Inventory. This will be the existing bucket in your account that has data that needs to be analyzed. This could be your data lake or application S3 bucket. We created the bucket s3-object-cost-allocation with some sample data and folder structure.
Choose Management.
Under Inventory configurations, choose Create inventory configuration.
For Inventory configuration name, enter s3-object-cost-allocation.
For Inventory scope, leave Prefix blank. This is to ensure that all objects are covered for the report.
For Object Versions, select Current version only.
For Report details, choose This account.
For Destination, choose the destination bucket we created (s3-inventory-configurations-<account_number>).
For Frequency, choose Daily.
For Output format, choose as Apache Parquet.
For Status, choose Enable.
Keep server-side encryption disabled. To use server-side encryption, choose Enable and specify the encryption key.
For Additional fields, select the following to add to the inventory report:
Size – The object size in bytes.
Last modified date – The object creation date or the last modified date, whichever is the latest.
Bucket key status – Indicates whether a bucket-level key generated by AWS KMS applies to the object.
Storage class – The storage class used for storing the object.
Intelligent-Tiering: Access tier – Indicates the access tier of the object if it was stored in Intelligent-Tie
Choose Create.
It may take up to 48 hours to deliver the first report.
Create AWS Glue Data Catalog tables for CUR and Amazon S3 Inventory reports
Wait for up to 48 hours for the previous step to generate the reports. In this section, we use Athena to create and define AWS Glue Data Catalog tables for the data that has been created using Cost and Usage Reports and Amazon S3 Inventory reports.
Athena is a serverless, interactive analytics service built on open-source frameworks, supporting open-table and file formats. Athena provides a simplified, flexible way to analyze petabytes of data where it lives.
Complete the following steps to create the tables using Athena:
Navigate to the Athena console.
If you’re using Athena for the first time, you need to set up a query result location in Amazon S3. If you preconfigured this in Athena , you can skip this step.
Choose View settings.
Choose Manage.
In the section Query result location and encryption, choose Browse S3 and choose the bucket that we created (athena-query-bucket-<account_number>).
Choose Save.
Navigate back to the Athena query editor.
Run the following query in Athena to create a table for Cost and Usage Reports. Verify and update the section for <<LOCATION>> at the end of the query and point it to the correct S3 bucket and location. Note that the new table name should be account_cur.
Run the following query in Athena to create the table for Amazon S3 Inventory. Verify and update the section for <<LOCATION>> at the end of the query and point it to the correct S3 bucket and location.
To get the exact value of the location, navigate to the bucket where inventory configurations are stored and navigate to the folder path Hive . Use the S3 URI to replace <<LOCATION>> in the query.
We need to refresh the partitions and add new inventory lists to the table. Use the following commands to add data to the CUR table and Amazon S3 Inventory table:
Run queries in Athena to allocate the cost of objects in an S3 bucket
Now we can query the data we have available to get a cost allocation breakdown at the prefix level.
We need to provide some information in the following queries:
Update <<YYYY-MM-DD>> with the date for which you want to analyze the data
Update <<prefix>> with the prefix values for your bucket that needs to be analyzed
Update <<bucket_name>> with the name of the bucket that needs to be analyzed
We use the following part of the query to calculate the size of storage being used by the target prefix that we want to calculate the cost for:
select date_parse(dt,'%Y-%m-%d-%H-%i') dt, cast (sum(size) as double) targetPrefixBytes
from s3_object_inventory
where date_parse(dt,'%Y-%m-%d-%H-%i') = cast('<<YYYY-MM-DD>>' as timestamp)
and key like '<<prefix>>/%'
group by dt
Next, we calculate the total size of the bucket on that particular date:
select date_parse(dt,'%Y-%m-%d-%H-%i') dt, cast (sum(size) as double) totalBytes
from s3_object_inventory
where date_parse(dt,'%Y-%m-%d-%H-%i') = cast('<<YYYY-MM-DD>>' as timestamp)
group by dt
We query the CUR table to get the cost of a particular bucket on a particular date:
select line_item_usage_start_date as dt, sum(line_item_blended_cost) as line_item_blended_cost
from "account_cur"
where line_item_product_code = 'AmazonS3'
and product_servicecode = 'AmazonS3'
and line_item_operation = 'StandardStorage'
and line_item_resource_id = '<<bucket_name>>'
and line_item_usage_start_date = cast('<<YYYY-MM-DD>>' as timestamp)
group by line_item_usage_start_date
Putting all of this together, we can calculate the cost of a particular prefix (folder or a file) on a specific date. The complete query is as follows:
with
cost as (select line_item_usage_start_date as dt, sum(line_item_blended_cost) as line_item_blended_cost
from "account_cur"
where line_item_product_code = 'AmazonS3'
and product_servicecode = 'AmazonS3'
and line_item_operation = 'StandardStorage'
and line_item_resource_id = '<<bucket_name>>'
and line_item_usage_start_date = cast('<<YYYY-MM-DD>>' as timestamp)
group by line_item_usage_start_date),
total as (select date_parse(dt,'%Y-%m-%d-%H-%i') dt, cast (sum(size) as double) totalBytes
from s3_object_inventory
where date_parse(dt,'%Y-%m-%d-%H-%i') = cast('<<YYYY-MM-DD>>' as timestamp)
group by dt),
target as (select date_parse(dt,'%Y-%m-%d-%H-%i') dt, cast (sum(size) as double) targetPrefixBytes
from s3_object_inventory
where date_parse(dt,'%Y-%m-%d-%H-%i') = cast('<<YYYY-MM-DD>>' as timestamp)
and key like '<<prefix>>/%'
group by dt)
select target.dt,
(target.targetPrefixBytes/ total.totalBytes * 100) percentUsed,
cost.line_item_blended_cost totalCost,
cost.line_item_blended_cost*(target.targetPrefixBytes/ total.totalBytes) as prefixCost
from target, total, cost
where target.dt = total.dt
and target.dt = cost.dt
The following screenshot shows the results table for the sample data we used in this post. We get the following information:
dt – Date
percentUsed – The percentage of prefix space compared to overall bucket space
totalCost – The total cost of the bucket
prefixCost – The cost of the space used by the prefix
Delete the S3 buckets created for the Amazon S3 Inventory reports and Cost and Usage Reports to avoid storage charges.
Other methods for Amazon S3 storage analysis
Amazon S3 Storage Lens can provide a single view of object storage usage and activity across your entire Amazon S3 storage. With S3 Storage Lens, you can understand, analyze, and optimize storage with over 29 usage and activity metrics and interactive dashboards to aggregate data for your entire organization, specific accounts, Regions, buckets, or prefixes. All of this data is accessible on the Amazon S3 console or as raw data in an S3 bucket.
S3 Storage Lens doesn’t provide cost analysis based on an object or prefix in a single bucket. If you want visibility of storage usage and trends across the entire storage footprint along with recommendations on cost efficiency and data protection best practices, S3 Storage Lens is the right option. But if you want a cost analysis of specific S3 buckets and looking for ways to get cost allocation of S3 objects at the object or prefix level, the solution in this post would be the best fit.
Conclusion
In this post, we detailed how to create a cost breakdown model at the object or prefix level for S3 buckets that contains data for multiple business units and applications. We used Athena to query the reports and datasets produced by the AWS CUR and Amazon S3 Inventory features that, when correlated, give us the cost allocation at the object and prefix level. This solution gives you an easy way to calculate costs for independent objects and prefixes, which can be used for internal chargebacks or just to know the per-object or per-prefix spending in a shared S3 bucket.
About the Authors
Dagar Katyal is a Senior Solutions Architect at AWS, based in Chicago, Illinois. He works with customers and provides guidance for key strategic initiatives important for their business. Dagar has an MBA and has spent years over 15 years working with customers on projects on analytics strategy, roadmap, and using data as a key differentiator. When not working with customers, Dagar spends time with his family and doing home improvement projects.
Saiteja Pudi is a Solutions Architect at AWS, based in Dallas, Tx. He has been with AWS for more than 3 years now, helping customers derive the true potential of AWS by being their trusted advisor. He comes from an application development background, interested in Data Science and Machine Learning.
This blog post is written by Enrico Liguori, SA – Solutions Builder , WWPS Solution Architecture.
AWS Local Zones are a type of infrastructure deployment that places compute, storage,and other select AWS services close to large population and industry centers.
We now have a total of 32 Local Zones; 15 outside of the US (Bangkok, Buenos Aires, Copenhagen, Delhi, Hamburg, Helsinki, Kolkata, Lagos, Lima, Muscat, Perth, Querétaro, Santiago, Taipei, and Warsaw) and 17 in the US. We will continue to launch Local Zones in 21 metro areas in 18 countries, including Australia, Austria, Belgium, Brazil, Canada, Colombia, Czech Republic, Germany, Greece, India, Kenya, Netherlands, New Zealand, Norway, Philippines, Portugal, South Africa, and Vietnam.
Customers using AWS Local Zones can provision the infrastructure and services needed to host their workloads with the same APIs and tools for automation that they use in the AWS Region, included the AWS Cloud Development Kit (AWS CDK).
The AWS CDK is an open source software development framework to model and provision your cloud application resources using familiar programming languages, including TypeScript, JavaScript, Python, C#, and Java. For the solution in this post, we use Python.
Overview
In this post we demonstrate how to:
Programmatically enable the Local Zone of your interest.
Explore the supported APIs to check the types of Amazon Elastic Compute Cloud (Amazon EC2) instances available in a specific Local Zone and get their associated price per hour;
Deploy a simple WordPress application in the Local Zone through AWS CDK.
Prerequisites
To be able to try the examples provided in this post, you must configure:
To get started with Local Zones, you must first enable the Local Zone that you plan to use in your AWS account. In this tutorial, you can learn how to select the Local Zone that provides the lowest latency to your site and understand how to opt into the Local Zone from the AWS Management Console.
If you prefer to interact with AWS APIs programmatically, then you can enable the Local Zone of your interest by calling the ModifyAvailabilityZoneGroup API through the AWS CLI or one of the supported AWS SDKs.
The following examples show how to opt into the Atlanta Local Zone through the AWS CLI and through the Python SDK:
The opt in process takes approximately five minutes to complete. After this time, you can confirm the opt in status using the DescribeAvailabilityZones API.
From the AWS CLI, you can check the enabled Local Zones with:
The OptInStatus confirms that we successful enabled the Atlanta Local Zone and that we can now deploy resources in it.
How to check available EC2 instances in Local Zones
The set of instance types available in a Local Zone might change from one Local Zone to another. This means that before starting deploying resources, it’s a good practice to check which instance types are supported in the Local Zone.
After enabling the Local Zone, we can programmatically check the instance types that are available by using DescribeInstanceTypeOfferings. To use the API with Local Zones, we must pass availability-zone as the value of the LocationType parameter and use a Filter object to select the correct Local Zone that we want to check. The resulting AWS CLI command will look like the following example:
How to check prices of EC2 instances in Local Zones
EC2 instances and other AWS resources in Local Zones will have different prices than in the parent Region. Check the pricing page for the complete list of pricing options and associated price-per-hour.
To access the pricing list programmatically, we can use the GetProducts API. The API returns the list of pricing options available for the AWS service specified in the ServiceCode parameter. We also recommend defining Filters to restrict the number of results returned. For example, to retrieve the On-Demand pricing list of a T3 Medium instance in Atlanta from the AWS CLI, we can use the following:
Note that the Region specified in the CLI command and in Boto3, is the location of the AWS Price List service API endpoint. This API is available only in us-east-1 and ap-south-1 Regions.
Deploying WordPress in Local Zones using AWS CDK
In this section, we see how to use the AWS CDK and Python to deploy a simple non-production WordPress installation in a Local Zone.
Architecture overview
The AWS CDK stack will deploy a new standard Amazon Virtual Private Cloud (Amazon VPC) in the parent Region (us-east-1) that will be extended to the Local Zone. This creates two subnets associated with the Atlanta Local Zone: a public subnet to expose resources on the Internet, and a private subnet to host the application and database layers. Review the AWS public documentation for a definition of public and private subnets in a VPC.
The application architecture is made of the following:
A front-end in the private subnet where a WordPress application is installed, through a User Data script, in a type T3 medium EC2 instance.
A back-end in the private subnet where MySQL database is installed, through a User Data script, in a type T3 medium EC2 instance.
Together with the VPC CIDR (i.e. 172.31.100.0/24), we define also the subnets configuration through the subnet_configuration parameter.
Note that in the subnet definitions above there is no specification of the Availability Zone or Local Zone that we want to associate them with. We can define this setting at the VPC level, overwriting the availability_zones method as shown here:
As an alternative, you can use a Local Zone Name as the value of the availability_zones parameter in each Subnet definition. For a complete list of Local Zone Names, check out the Zone Names on the Local Zones Locations page.
Specifying ec2.SubnetType.PUBLIC in the subnet_type parameter, AWS CDK automatically creates an Internet Gateway (IGW) associated with our VPC and a default route in its routing table pointing to the IGW. With this setup, the Internet traffic will go directly to the IGW in the Local Zone without going through the parent AWS Region. For other connectivity options, check the AWS Local Zone User Guide.
The last piece of our networking infrastructure is a self-managed NAT instance. This will allow instances in the private subnet to communicate with services outside of the VPC and simultaneously prevent them from receiving unsolicited connection requests.
We can implement the best practices for NAT instances included in the AWS public documentation using a combination of parameters of the Instance construct, as shown here:
In the previous code example, we specify the following as parameters:
vpc – the VPC object created before.
security group – the Security Group containing the rules to allow HTTP and HTTPS traffic. The Security Group is created in create_nat_SG function provided in the code that we copied from the repository.
instance_type – the instance type, in our case a T3 Medium.
The other resources, including the front-end instance managed by AutoScaling, the back-end instance, and ALB are deployed using the standard AWS CDK constructs. Note that the ALB service is only available in some Local Zones. If you plan to use a Local Zone where ALB isn’t supported, then you must deploy a load balancer on a self-managed EC2 instance, or use a load balancer available in AWS Marketplace.
Stack deployment
Next, let’s go through the AWS CDK bootstrapping process. This is required only for the first time that we use AWS CDK in a specific AWS environment (an AWS environment is a combination of an AWS account and Region).
$ cdk bootstrap
Now we can deploy the stack with the following:
$ cdk deploy
After the deployment is completed, we can connect to the application with a browser using the URL returned in the output of the cdk deploy command:
The WordPress install wizard will be displayed in the browser, thereby confirming that the deployment worked as expected:
Note that in this post we use the Local Zone in Atlanta. Therefore, we must deploy the stack in its parent Region, US East (N. Virginia). To select the Region used by the stack, configure the AWS CLI default profile.
Cleanup
To terminate the resources that we created in this post, you can simply run the following:
$ cdk destroy
Conclusion
In this post, we demonstrated how to interact programmatically with the different AWS APIs available for Local Zones. Furthermore, we deployed a simple WordPress application in the Atlanta Local Zone after analyzing the AWS CDK code used for the deployment.
We encourage you to try the examples provided in this post and get familiar with the programmatic configuration and deployment of resources in a Local Zone.
Secrets managers are a great tool to securely store your secrets and provide access to secret material to a set of individuals, applications, or systems that you trust. Across your environments, you might have multiple secrets managers hosted on different providers, which can increase the complexity of maintaining a consistent operating model for your secrets. In these situations, centralizing your secrets in a single source of truth, and replicating subsets of secrets across your other secrets managers, can simplify your operating model.
This blog post explains how you can use your third-party secrets manager as the source of truth for your secrets, while replicating a subset of these secrets to AWS Secrets Manager. By doing this, you will be able to use secrets that originate and are managed from your third-party secrets manager in Amazon Web Services (AWS) applications or in AWS services that use Secrets Manager secrets.
I’ll demonstrate this approach in this post by setting up a sample open-source HashiCorp Vault to create and maintain secrets and create a replication mechanism that enables you to use these secrets in AWS by using AWS Secrets Manager. Although this post uses HashiCorp Vault as an example, you can also modify the replication mechanism to use secrets managers from other providers.
Important: This blog post is intended to provide guidance that you can use when planning and implementing a secrets replication mechanism. The examples in this post are not intended to be run directly in production, and you will need to take security hardening requirements into consideration before deploying this solution. As an example, HashiCorp provides tutorials on hardening production vaults.
You can use these links to navigate through this post:
The primary use case for this post is for customers who are running applications on AWS and are currently using a third-party secrets manager to manage their secrets, hosted on-premises, in the AWS Cloud, or with a third-party provider. These customers typically have existing secrets vending processes, deployment pipelines, and procedures and processes around the management of these secrets. Customers with such a setup might want to keep their existing third-party secrets manager and have a set of secrets that are accessible to workloads running outside of AWS, as well as workloads running within AWS, by using AWS Secrets Manager.
Another use case is for customers who are in the process of migrating workloads to the AWS Cloud and want to maintain a (temporary) hybrid form of secrets management. By replicating secrets from an existing third-party secrets manager, customers can migrate their secrets to the AWS Cloud one-by-one, test that they work, integrate the secrets with the intended applications and systems, and once the migration is complete, remove the third-party secrets manager.
Additionally, some AWS services, such as Amazon Relational Database Service (Amazon RDS) Proxy, AWS Direct Connect MACsec, and AD Connector seamless join (Linux), only support secrets from AWS Secrets Manager. Customers can use secret replication if they have a third-party secrets manager and want to be able to use third-party secrets in services that require integration with AWS Secrets Manager. That way, customers don’t have to manage secrets in two places.
Two approaches to secrets replication
In this post, I’ll discuss two main models to replicate secrets from an external third-party secrets manager to AWS Secrets Manager: a pull model and a push model.
Pull model In a pull model, you can use AWS services such as Amazon EventBridge and AWS Lambda to periodically call your external secrets manager to fetch secrets and updates to those secrets. The main benefit of this model is that it doesn’t require any major configuration to your third-party secrets manager. The AWS resources and mechanism used for pulling secrets must have appropriate permissions and network access to those secrets. However, there could be a delay between the time a secret is created and updated and when it’s picked up for replication, depending on the time interval configured between pulls from AWS to the external secrets manager.
Push model In this model, rather than periodically polling for updates, the external secrets manager pushes updates to AWS Secrets Manager as soon as a secret is added or changed. The main benefit of this is that there is minimal delay between secret creation, or secret updating, and when that data is available in AWS Secrets Manager. The push model also minimizes the network traffic required for replication since it’s a unidirectional flow. However, this model adds a layer of complexity to the replication, because it requires additional configuration in the third-party secrets manager. More specifically, the push model is dependent on the third-party secrets manager’s ability to run event-based push integrations with AWS resources. This will require a custom integration to be developed and managed on the third-party secrets manager’s side.
This blog post focuses on the pull model to provide an example integration that requires no additional configuration on the third-party secrets manager.
Replicate secrets to AWS Secrets Manager with the pull model
In this section, I’ll walk through an example of how to use the pull model to replicate your secrets from an external secrets manager to AWS Secrets Manager.
Solution overview
Figure 1: Secret replication architecture diagram
The architecture shown in Figure 1 consists of the following main steps, numbered in the diagram:
A Cron expression in Amazon EventBridge invokes an AWS Lambda function every 30 minutes.
To connect to the third-party secrets manager, the Lambda function, written in NodeJS, fetches a set of user-defined API keys belonging to the secrets manager from AWS Secrets Manager. These API keys have been scoped down to give read-only access to secrets that should be replicated, to adhere to the principle of least privilege. There is more information on this in Step 3: Update the Vault connection secret.
The third step has two variants depending on where your third-party secrets manager is hosted:
The Lambda function is configured to fetch secrets from a third-party secrets manager that is hosted outside AWS. This requires sufficient networking and routing to allow communication from the Lambda function.
Note: Depending on the location of your third-party secrets manager, you might have to consider different networking topologies. For example, you might need to set up hybrid connectivity between your external environment and the AWS Cloud by using AWS Site-to-Site VPN or AWS Direct Connect, or both.
Important: To simplify the deployment of this example integration, I’ll use a secrets manager hosted on a publicly available Amazon EC2 instance within the same VPC as the Lambda function (3b). This minimizes the additional networking components required to interact with the secrets manager. More specifically, the EC2 instance runs an open-source HashiCorp Vault. In the rest of this post, I’ll refer to the HashiCorp Vault’s API keys as Vault tokens.
The Lambda function compares the version of the secret that it just fetched from the third-party secrets manager against the version of the secret that it has in AWS Secrets Manager (by tag). The function will create a new secret in AWS Secrets Manager if the secret does not exist yet, and will update it if there is a new version. The Lambda function will only consider secrets from the third-party secrets manager for replication if they match a specified prefix. For example, hybrid-aws-secrets/.
In case there is an error synchronizing the secret, an email notification is sent to the email addresses which are subscribed to the Amazon Simple Notification Service (Amazon SNS) Topic deployed. This sample application uses email notifications with Amazon SNS as an example, but you could also integrate with services like ServiceNow, Jira, Slack, or PagerDuty. Learn more about how to use webhooks to publish Amazon SNS messages to external services.
Step 1: Deploy the solution by using the AWS CDK toolkit
For this blog post, I’ve created an AWS Cloud Development Kit (AWS CDK) script, which can be found in this AWS GitHub repository. Using the AWS CDK, I’ve defined the infrastructure depicted in Figure 1 as Infrastructure as Code (IaC), written in TypeScript, ready for you to deploy and try out. The AWS CDK is an open-source software development framework that allows you to write your cloud application infrastructure as code using common programming languages such as TypeScript, Python, Java, Go, and so on.
Prerequisites:
To deploy the solution, the following should be in place on your system:
AWS CDK Toolkit. Install using npm (included in Node setup) by running npm install -g aws-cdk in a local terminal.
An AWS access key ID and secret access key configured as this setup will interact with your AWS account. See Configuration basics in the AWS Command Line Interface User Guide for more details.
Clone the CDK script for secret replication. git clone https://github.com/aws-samples/aws-secrets-manager-hybrid-secret-replication-from-hashicorp-vault.git SecretReplication
Use the cloned project as the working directory. cd SecretReplication
Install the required dependencies to deploy the application. npm install
Adjust any configuration values for your setup in the cdk.json file. For example, you can adjust the secretsPrefix value to change which prefix is used by the Lambda function to determine the subset of secrets that should be replicated from the third-party secrets manager.
Bootstrap your AWS environments with some resources that are required to deploy the solution. With correctly configured AWS credentials, run the following command. cdk bootstrap
This command deploys the infrastructure shown in Figure 1 for you by using AWS CloudFormation. For a full list of resources, you can view the SecretsManagerReplicationStack in AWS CloudFormation after the deployment has completed.
Note: If your local environment does not have a terminal that allows you to run these commands, consider using AWS Cloud9 or AWS CloudShell.
After the deployment has finished, you should see an output in your terminal that looks like the one shown in Figure 2. If successful, the output provides the IP address of the sample HashiCorp Vault and its web interface.
Figure 2: AWS CDK deployment output
Step 2: Initialize the HashiCorp Vault
As part of the output of the deployment script, you will be given a URL to access the user interface of the open-source HashiCorp Vault. To simplify accessibility, the URL points to a publicly available Amazon EC2 instance running the HashiCorp Vault user interface as shown in step 3b in Figure 1.
Let’s look at the HashiCorp Vault that was just created. Go to the URL in your browser, and you should see the Raft Storage initialize page, as shown in Figure 3.
The vault requires an initial configuration to set up storage and get the initial set of root keys. You can go through the steps manually in the HashiCorp Vault’s user interface, but I recommend that you use the initialise_vault.sh script that is included as part of the SecretsManagerReplication project instead.
Using the HashiCorp Vault API, the initialization script will automatically do the following:
Initialize the Raft storage to allow the Vault to store secrets locally on the instance.
Create an initial set of unseal keys for the Vault. Importantly, for demo purposes, the script uses a single key share. For production environments, it’s recommended to use multiple key shares so that multiple shares are needed to reconstruct the root key, in case of an emergency.
Store the unseal keys in init/vault_init_output.json in your project.
Unseals the HashiCorp Vault by using the unseal keys generated earlier.
Enables two key-value secrets engines:
An engine named after the prefix that you’re using for replication, defined in the cdk.json file. In this example, this is hybrid-aws-secrets. We’re going to use the secrets in this engine for replication to AWS Secrets Manager.
An engine called super-secret-engine, which you’re going to use to show that your replication mechanism does not have access to secrets outside the engine used for replication.
Creates three example secrets, two in hybrid-aws-secrets, and one in super-secret-engine.
Creates a read-only policy, which you can see in the init/replication-policy-payload.json file after the script has finished running, that allows read-only access to only the secrets that should be replicated.
Creates a new vault token that has the read-only policy attached so that it can be used by the AWS Lambda function later on to fetch secrets for replication.
To run the initialization script, go back to your terminal, and run the following command. ./initialise_vault.sh
The script will then ask you for the IP address of your HashiCorp Vault. Provide the IP address (excluding the port) and choose Enter. Input y so that the script creates a couple of sample secrets.
If everything is successful, you should see an output that includes tokens to access your HashiCorp Vault, similar to that shown in Figure 4.
The setup script has outputted two tokens: one root token that you will use for administrator tasks, and a read-only token that will be used to read secret information for replication. Make sure that you can access these tokens while you’re following the rest of the steps in this post.
Note: The root token is only used for demonstration purposes in this post. In your production environments, you should not use root tokens for regular administrator actions. Instead, you should use scoped down roles depending on your organizational needs. In this case, the root token is used to highlight that there are secrets under super-secret-engine/ which are not meant for replication. These secrets cannot be seen, or accessed, by the read-only token.
Go back to your browser and refresh your HashiCorp Vault UI. You should now see the Sign in to Vault page. Sign in using the Token method, and use the root token. If you don’t have the root token in your terminal anymore, you can find it in the init/vault_init_output.json file.
After you sign in, you should see the overview page with three secrets engines enabled for you, as shown in Figure 5.
If you explore hybrid-aws-secrets and super-secret-engine, you can see the secrets that were automatically created by the initialization script. For example, first-secret-for-replication, which contains a sample key-value secret with the key secrets and value manager.
If you navigate to Policies in the top navigation bar, you can also see the aws-replication-read-only policy, as shown in Figure 6. This policy provides read-only access to only the hybrid-aws-secrets path.
Figure 6: Read-only HashiCorp Vault token policy
The read-only policy is attached to the read-only token that we’re going to use in the secret replication Lambda function. This policy is important because it scopes down the access that the Lambda function obtains by using the token to a specific prefix meant for replication. For secret replication we only need to perform read operations. This policy ensures that we can read, but cannot add, alter, or delete any secrets in HashiCorp Vault using the token.
You can verify the read-only token permissions by signing into the HashiCorp Vault user interface using the read-only token rather than the root token. Now, you should only see hybrid-aws-secrets. You no longer have access to super-secret-engine, which you saw in Figure 5. If you try to create or update a secret, you will get a permission denied error.
Great! Your HashiCorp Vault is now ready to have its secrets replicated from hybrid-aws-secrets to AWS Secrets Manager. The next section describes a final configuration that you need to do to allow access to the secrets in HashiCorp Vault by the replication mechanism in AWS.
Step 3: Update the Vault connection secret
To allow secret replication, you must give the AWS Lambda function access to the HashiCorp Vault read-only token that was created by the initialization script. To do that, you need to update the vault-connection-secret that was initialized in AWS Secrets Manager as part of your AWS CDK deployment.
For demonstration purposes, I’ll show you how to do that by using the AWS Management Console, but you can also do it programmatically by using the AWS Command Line Interface (AWS CLI) or AWS SDK with the update-secret command.
To update the Vault connection secret (console)
In the AWS Management Console, go to AWS Secrets Manager > Secrets > hybrid-aws-secrets/vault-connection-secret.
Under Secret Value, choose Retrieve Secret Value, and then choose Edit.
Update the vaultToken value to contain the read-only token that was generated by the initialization script.
Step 4: (Optional) Set up email notifications for replication failures
As highlighted in Figure 1, the Lambda function will send an email by using Amazon SNS to a designated email address whenever one or more secrets fails to be replicated. You will need to configure the solution to use the correct email address. To do this, go to the cdk.json file at the root of the SecretReplication folder and adjust the notificationEmail parameter to an email address that you own. Once done, deploy the changes using the cdk deploy command. Within a few minutes, you’ll get an email requesting you to confirm the subscription. Going forward, you will receive an email notification if one or more secrets fails to replicate.
Test your secret replication
You can either wait up to 30 minutes for the Lambda function to be invoked automatically to replicate the secrets, or you can manually invoke the function.
To test your secret replication
Open the AWS Lambda console and find the Secret Replication function (the name starts with SecretsManagerReplication-SecretReplication).
Navigate to the Test tab.
For the text event action, select Create new event, create an event using the default parameters, and then choose the Test button on the right-hand side, as shown in Figure 8.
Figure 8: AWS Lambda – Test page to manually invoke the function
This will run the function. You should see a success message, as shown in Figure 9. If this is the first time the Lambda function has been invoked, you will see in the results that two secrets have been created.
Figure 9: AWS Lambda function output
You can find the corresponding logs for the Lambda function invocation in a Log group in AWS CloudWatch matching the name /aws/lambda/SecretsManagerReplication-SecretReplicationLambdaF-XXXX.
To verify that the secrets were added, navigate to AWS Secrets Manager in the console, and in addition to the vault-connection-secret that you edited before, you should now also see the two new secrets with the same hybrid-aws-secrets prefix, as shown in Figure 10.
Figure 10: AWS Secrets Manager overview – New replicated secrets
For example, if you look at first-secret-for-replication, you can see the first version of the secret, with the secret key secrets and secret value manager, as shown in Figure 11.
Figure 11: AWS Secrets Manager – New secret overview showing values and version number
Success! You now have access to the secret values that originate from HashiCorp Vault in AWS Secrets Manager. Also, notice how there is a version tag attached to the secret. This is something that is necessary to update the secret, which you will learn more about in the next two sections.
Update a secret
It’s a recommended security practice to rotate secrets frequently. The Lambda function in this solution not only replicates secrets when they are created — it also periodically checks if existing secrets in AWS Secrets Manager should be updated when the third-party secrets manager (HashiCorp Vault in this case) has a new version of the secret. To validate that this works, you can manually update a secret in your HashiCorp Vault and observe its replication in AWS Secrets Manager in the same way as described in the previous section. You will notice that the version tag of your secret gets updated automatically when there is a new secret replication from the third-party secrets manager to AWS Secrets Manager.
Secret replication logic
This section will explain in more detail the logic behind the secret replication. Consider the following sequence diagram, which explains the overall logic implemented in the Lambda function.
Figure 12: State diagram for secret replication logic
This diagram highlights that the Lambda function will first fetch a list of secret names from the HashiCorp Vault. Then, the function will get a list of secrets from AWS Secrets Manager, matching the prefix that was configured for replication. AWS Secrets Manager will return a list of the secrets that match this prefix and will also return their metadata and tags. Note that the function has not fetched any secret material yet.
Next, the function will loop through each secret name that HashiCorp Vault gave and will check if the secret exists in AWS Secrets Manager:
If there is no secret that matches that name, the function will fetch the secret material from HashiCorp Vault, including the version number, and create a new secret in AWS Secrets Manager. It will also add a version tag to the secret to match the version.
If there is a secret matching that name in AWS Secrets Manager already, the Lambda function will first fetch the metadata from that secret in HashiCorp Vault. This is required to get the version number of the secret, because the version number was not exposed when the function got the list of secrets from HashiCorp Vault initially. If the secret version from HashiCorp Vault does not match the version value of the secret in AWS Secrets Manager (for example, the version in HashiCorp vault is 2, and the version in AWS Secrets manager is 1), an update is required to get the values synchronized again. Only now will the Lambda function fetch the actual secret material from HashiCorp Vault and update the secret in AWS Secrets Manager, including the version number in the tag.
The Lambda function fetches metadata about the secrets, rather than just fetching the secret material from HashiCorp Vault straight away. Typically, secrets don’t update very often. If this Lambda function is called every 30 minutes, then it should not have to add or update any secrets in the majority of invocations. By using metadata to determine whether you need the secret material to create or update secrets, you minimize the number of times secret material is fetched both from HashiCorp Vault and AWS Secrets Manager.
Note: The AWS Lambda function has permissions to pull certain secrets from HashiCorp Vault. It is important to thoroughly review the Lambda code and any subsequent changes to it to prevent leakage of secrets. For example, you should ensure that the Lambda function does not get updated with code that unintentionally logs secret material outside the Lambda function.
Use your secret
Now that you have created and replicated your secrets, you can use them in your AWS applications or AWS services that are integrated with Secrets Manager. For example, you can use the secrets when you set up connectivity for a proxy in Amazon RDS, as follows.
To use a secret when creating a proxy in Amazon RDS
Go to the Amazon RDS service in the console.
In the left navigation pane, choose Proxies, and then choose Create Proxy.
On the Connectivity tab, you can now select first-secret-for-replicationorsecond-secret-for-replication, which were created by the Lambda function after replicating them from the HashiCorp Vault.
Figure 13: Amazon RDS Proxy – Example of using replicated AWS Secrets Manager secrets
Due to the sensitive nature of the secrets, it is important that you scope down the permissions to the least amount required to prevent inadvertent access to your secrets. The setup adopts a least-privilege permission strategy, where only the necessary actions are explicitly allowed on the resources that are required for replication. However, the permissions should be reviewed in accordance to your security standards.
In the architecture of this solution, there are two main places where you control access to the management of your secrets in Secrets Manager.
Lambda execution IAM role: The IAM role assumed by the Lambda function during execution contains the appropriate permissions for secret replication. There is an additional safety measure, which explicitly denies any action to a resource that is not required for the replication. For example, the Lambda function only has permission to publish to the Amazon SNS topic that is created for the failed replications, and will explicitly deny a publish action to any other topic. Even if someone accidentally adds an allow to the policy for a different topic, the explicit deny will still block this action.
AWS KMS key policy: When other services need to access the replicated secret in AWS Secrets Manager, they need permission to use the hybrid-aws-secrets-encryption-key AWS KMS key. You need to allow the principal these permissions through the AWS KMS key policy. Additionally, you can manage permissions to the AWS KMS key for the principal through an identity policy. For example, this is required when accessing AWS KMS keys across AWS accounts. See Permissions for AWS services in key policies and Specifying KMS keys in IAM policy statements in the AWS KMS Developer Guide.
Options for customizing the sample solution
The solution that was covered in this post provides an example for replication of secrets from HashiCorp Vault to AWS Secrets Manager using the pull model. This section contains additional customization options that you can consider when setting up the solution, or your own variation of it.
Depending on the solution that you’re using, you might have access to different metadata attached to the secrets, which you can use to determine if a secret should be updated. For example, if you have access to data that represents a last_updated_datetime property, you could use this to infer whether or not a secret ought to be updated.
It is a recommended practice to not use long-lived tokens wherever possible. In this sample, I used a static vault token to give the Lambda function access to the HashiCorp Vault. Depending on the solution that you’re using, you might be able to implement better authentication and authorization mechanisms. For example, HashiCorp Vault allows you to use IAM auth by using AWS IAM, rather than a static token.
This post addressed the creation of secrets and updating of secrets, but for your production setup, you should also consider deletion of secrets. Depending on your requirements, you can choose to implement a strategy that works best for you to handle secrets in AWS Secrets Manager once the original secret in HashiCorp Vault has been deleted. In the pull model, you could consider removing a secret in AWS Secrets Manager if the corresponding secret in your external secrets manager is no longer present.
In the sample setup, the same AWS KMS key is used to encrypt both the environment variables of the Lambda function, and the secrets in AWS Secrets Manager. You could choose to add an additional AWS KMS key (which would incur additional cost), to have two separate keys for these tasks. This would allow you to apply more granular permissions for the two keys in the corresponding KMS key policies or IAM identity policies that use the keys.
Conclusion
In this blog post, you’ve seen how you can approach replicating your secrets from an external secrets manager to AWS Secrets Manager. This post focused on a pull model, where the solution periodically fetched secrets from an external HashiCorp Vault and automatically created or updated the corresponding secret in AWS Secrets Manager. By using this model, you can now use your external secrets in your AWS Cloud applications or services that have an integration with AWS Secrets Manager.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Secrets Manager re:Post or contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
Today, we are launching a new reference architecture and a set of reference implementations for enterprise-grade deployment pipelines. A deployment pipeline automates the building, testing, and deploying of applications or infrastructures into your AWS environments. When you deploy your workloads to the cloud, having deployment pipelines is key to gaining agility and lowering time to market.
When I talk with you at conferences or on social media, I frequently hear that our documentation and tutorials are good resources to get started with a new service or a new concept. However, when you want to scale your usage or when you have complex or enterprise-grade use cases, you often lack resources to dive deeper.
We used the best practices and lessons learned at Amazon and with hundreds of customer projects to create this deployment pipeline reference architecture and implementations. They go well beyond the typical “Hello World” example: They document how to architect and how to implement complex deployment pipelines with multiple environments, multiple AWS accounts, multiple Regions, manual approval, automated testing, automated code analysis, etc. When you want to increase the speed at which you deliver software to your customers through DevOps and continuous delivery, this new reference architecture shows you how to combine AWS services to work together. They document the mandatory and optional components of the architecture.
Having an architecture document and diagram is great, but having an implementation is even better. Each pipeline type in the reference architecture has at least one reference implementation. One of the reference implementations uses an AWS Cloud Development Kit (AWS CDK) application to deploy the reference architecture on your accounts. It is a good starting point to study or customize the reference architecture to fit your specific requirements.
Let’s Deploy a Reference Implementation The new deployment pipeline reference architecture demonstrates how to build a pipeline to deploy a Java containerized application and a database. It comes with two reference implementations. We are working on additional pipeline types to deploy Amazon EC2 AMIs, manage a fleet of accounts, and manage dynamic configuration for your applications.
The sample application is developed with SpringBoot. It runs on top of Corretto, the Amazon-provided distribution of the OpenJDK. The application is packaged with the CDK and is deployed on AWS Fargate. But the application is not important here; you can substitute your own application. The important parts are the infrastructure components and the pipeline to deploy an application. For this pipeline type, we provide two reference implementations. One deploys the application using Amazon CodeCatalyst, the new service that we announced at re:Invent 2022, and one uses AWS CodePipeline. This is the one I choose to deploy for this blog post.
The pipeline starts building the applications with AWS CodeBuild. It runs the unit tests and also runs Amazon CodeGuru to review code quality and security. Finally, it runs Trivy to detect additional security concerns, such as known vulnerabilities in the application dependencies. When the build is successful, the pipeline deploys the application in three environments: beta, gamma, and production. It deploys the application in the beta environment in a single Region. The pipeline runs end-to-end tests in the beta environment. All the tests must succeed before the deployment continues to the gamma environment. The gamma environment uses two Regions to host the application. After deployment in the gamma environment, the deployment into production is subject to manual approval. Finally, the pipeline deploys the application in the production environment in six Regions, with three waves of deployments made of two Regions each.
I need four AWS accounts to deploy this reference implementation: one to deploy the pipeline and tooling and one for each environment (beta, gamma, and production). At a high level, there are two deployment steps: first, I bootstrap the CDK for all four accounts, and then I create the pipeline itself in the toolchain account. You must plan for 2-3 hours of your time to prepare your accounts, create the pipeline, and go through a first deployment.
Once the pipeline is created, it builds, tests, and deploys the sample application from its source in AWS CodeCommit. You can commit and push changes to the application source code and see it going through the pipeline steps again.
Available Now The deployment pipeline reference architecture and its reference implementations are available today, free of charge. If you decide to deploy a reference implementation, we will charge you for the resources it creates on your accounts. You can use the provided AWS CDK code and the detailed instructions to deploy this pipeline on your AWS accounts. Try them today!
The Amazon EMR runtime for Apache Spark is a performance-optimized runtime for Apache Spark that is 100% API compatible with open-source Apache Spark. With Amazon EMR release 6.9.0, the EMR runtime for Apache Spark supports equivalent Spark version 3.3.0.
With Amazon EMR 6.9.0, you can now run your Apache Spark 3.x applications faster and at lower cost without requiring any changes to your applications. In our performance benchmark tests, derived from TPC-DS performance tests at 3 TB scale, we found the EMR runtime for Apache Spark 3.3.0 provides a 3.5 times (using total runtime) performance improvement on average over open-source Apache Spark 3.3.0.
In this post, we analyze the results from our benchmark tests running a TPC-DS application on open-source Apache Spark and then on Amazon EMR 6.9, which comes with an optimized Spark runtime that is compatible with open-source Spark. We walk through a detailed cost analysis and finally provide step-by-step instructions to run the benchmark.
Results observed
To evaluate the performance improvements, we used an open-source Spark performance test utility that is derived from the TPC-DS performance test toolkit. We ran the tests on a seven-node (six core nodes and one primary node) c5d.9xlarge EMR cluster with the EMR runtime for Apache Spark, and a second seven-node self-managed cluster on Amazon Elastic Compute Cloud (Amazon EC2) with the equivalent open-source version of Spark. We ran both the tests with data in Amazon Simple Storage Service (Amazon S3).
Dynamic Resource Allocation (DRA) is a great feature to use for varying workloads. However, for a benchmarking exercise where we compare two platforms purely on performance, and test data volumes don’t change (3 TB in our case), we believe it’s best to avoid variability in order to run an apples-to-apples comparison. In our tests in both open-source Spark and Amazon EMR, we disabled DRA while running the benchmarking application.
The following table shows the total job runtime for all queries (in seconds) in the 3 TB query dataset between Amazon EMR version 6.9.0 and open-source Spark version 3.3.0. We observed that our TPC-DS tests had a total job runtime on Amazon EMR on Amazon EC2 that was 3.5 times faster than that using an open-source Spark cluster of the same configuration.
The per-query speedup on Amazon EMR 6.9 with and without the EMR runtime for Apache Spark is illustrated in the following chart. The horizontal axis shows each query in the 3 TB benchmark. The vertical axis shows the speedup of each query due to the EMR runtime. Notable performance gains are over 10 times faster for TPC-DS queries 24b, 72, 95, and 96.
Cost analysis
The performance improvements of the EMR runtime for Apache Spark directly translate to lower costs. We were able to realize a 67% cost savings running the benchmark application on Amazon EMR in comparison with the cost incurred to run the same application on open-source Spark on Amazon EC2 with the same cluster sizing due to reduced hours of Amazon EMR and Amazon EC2 usage. Amazon EMR pricing is for EMR applications running on EMR clusters with EC2 instances. The Amazon EMR price is added to the underlying compute and storage prices such as EC2 instance price and Amazon Elastic Block Store (Amazon EBS) cost (if attaching EBS volumes). Overall, the estimated benchmark cost in the US East (N. Virginia) Region is $27.01 per run for the open-source Spark on Amazon EC2 and $8.82 per run for Amazon EMR.
Benchmark Job
Runtime (Hour)
Estimated Cost
Total EC2 Instance
Total vCPU
Total Memory (GiB)
Root Device (Amazon EBS)
Open-source Spark on Amazon EC2
(1 primary and 6 core nodes)
2.23
$27.01
7
252
504
20 GiB gp2
Amazon EMR on Amazon EC2
(1 primary and 6 core nodes)
0.63
$8.82
7
252
504
20 GiB gp2
Cost breakdown
The following is the cost breakdown for the open-source Spark on Amazon EC2 job ($27.01):
Total Amazon EC2 cost – (7 * $1.728 * 2.23) = (number of instances * c5d.9xlarge hourly rate * job runtime in hour) = $26.97
Amazon EBS cost – ($0.1/730 * 20 * 7 * 2.23) = (Amazon EBS per GB-hourly rate * root EBS size * number of instances * job runtime in hour) = $0.042
The following is the cost breakdown for the Amazon EMR on Amazon EC2 job ($8.82):
Total Amazon EMR cost – (7 * $0.27 * 0.63) = ((number of core nodes + number of primary nodes)* c5d.9xlarge Amazon EMR price * job runtime in hour) = $1.19
Total Amazon EC2 cost – (7 * $1.728 * 0.63) = ((number of core nodes + number of primary nodes)* c5d.9xlarge instance price * job runtime in hour) = $7.62
Amazon EBS cost – ($0.1/730 * 20 GiB * 7 * 0.63) = (Amazon EBS per GB-hourly rate * EBS size * number of instances * job runtime in hour) = $0.012
Set up OSS Spark benchmarking
In the following sections, we provide a brief outline of the steps involved in setting up the benchmarking. For detailed instructions with examples, refer to the GitHub repo.
For our OSS Spark benchmarking, we use the open-source tool Flintrock to launch our Amazon EC2-based Apache Spark cluster. Flintrock provides a quick way to launch an Apache Spark cluster on Amazon EC2 using the command line.
Prerequisites
Complete the following prerequisite steps:
Have Python 3.7.x or above.
Have Pip3 22.2.2 or above.
Add the Python bin directory to your environment path. The Flintrock binary will be installed in this path.
Run the command flintrock configure, which pops up a default configuration file.
Modify the default config.yaml file based on your needs. Alternatively, copy and paste the config.yaml file content to the default configure file. Then save the file to where it was.
Finally, launch the 7-node Spark cluster on Amazon EC2 via Flintrock.
This should create a Spark cluster with one primary node and six worker nodes. If you see any error messages, double-check the config file values, especially the Spark and Hadoop versions and the attributes of download-source and the AMI.
The OSS Spark cluster doesn’t come with YARN resource manager. To enable it, we need to configure the cluster.
Download the test result file from the output S3 bucket s3://$YOUR_S3_BUCKET/EC2_TPCDS-TEST-3T-RESULT/timestamp=xxxx/summary.csv/xxx.csv. (Replace $YOUR_S3_BUCKET with your S3 bucket name.) You can use the Amazon S3 console and navigate to the output S3 location or use the AWS CLI.
The Spark benchmark application creates a timestamp folder and writes a summary file inside a summary.csv prefix. Your timestamp and file name will be different from the one shown in the preceding example.
The output CSV files have four columns without header names. They are:
Query name
Median time
Minimum time
Maximum time
The following screenshot shows a sample output. We have manually added column names. The way we calculate the geomean and the total job runtime is based on arithmetic means. We first take the mean of the med, min, and max values using the formula AVERAGE(B2:D2). Then we take a geometric mean of the Avg column using the formula GEOMEAN(E2:E105).
Run aws configure to configure your AWS CLI shell to point to the benchmarking account. Refer to Quick configuration with aws configure for instructions.
Configure Amazon EMR with one primary (c5d.9xlarge) and six core (c5d.9xlarge) nodes. Refer to create-cluster for a detailed description of AWS CLI options.
Store the cluster ID from the response. You need this in the next step.
Submit the benchmark job in Amazon EMR using add-steps in the AWS CLI.
Summarize the results
Summarize the results from the output bucket s3://$YOUR_S3_BUCKET/blog/EMRONEC2_TPCDS-TEST-3T-RESULT in the same manner as we did for the OSS results and compare.
Stop the EMR and OSS Spark clusters. You may also delete them if you don’t want to retain the content. You can delete these resources by running the script cleanup-benchmark-env.sh from a terminal in your benchmark environment.
You can run your Apache Spark workloads 3.5 times (based on total runtime) faster and at lower cost without making any changes to your applications by using Amazon EMR 6.9.0.
To keep up to date, subscribe to the Big Data Blog’s RSS feed to learn more about the EMR runtime for Apache Spark, configuration best practices, and tuning advice.
Sekar Srinivasan is a Sr. Specialist Solutions Architect at AWS focused on Big Data and Analytics. Sekar has over 20 years of experience working with data. He is passionate about helping customers build scalable solutions modernizing their architecture and generating insights from their data. In his spare time he likes to work on non-profit projects, especially those focused on underprivileged Children’s education.
Prabu Ravichandran is a Senior Data Architect with Amazon Web Services, focussed on Analytics, data Lake architecture and implementation. He helps customers architect and build scalable and robust solutions using AWS services. In his free time, Prabu enjoys traveling and spending time with family.
As organizations continue to grow and scale their applications, the need for teams to be able to quickly and autonomously detect anomalous operational behaviors becomes increasingly important. Amazon DevOps Guru offers a fully managed AIOps service that enables you to improve application availability and resolve operational issues quickly. DevOps Guru helps ease this process by leveraging machine learning (ML) powered recommendations to detect operational insights, identify the exhaustion of resources, and provide suggestions to remediate issues. Many organizations running business critical applications use different tools to be notified about anomalous events in real-time for the remediation of critical issues. Atlassian is a modern team collaboration and productivity software suite that helps teams organize, discuss, and complete shared work. You can deliver these insights in near-real time to DevOps teams by integrating DevOps Guru with Atlassian Opsgenie. Opsgenie is a modern incident management platform that receives alerts from your monitoring systems and custom applications and categorizes each alert based on importance and timing.
This blog post walks you through how to integrate Amazon DevOps Guru with Atlassian Opsgenie to receive notifications for new operational insights detected by DevOps Guru with more flexibility and customization using Amazon EventBridge and AWS Lambda. The Lambda function will be used to demonstrate how to customize insights sent to Opsgenie.
Solution overview
Figure 1: Amazon EventBridge Integration with Opsgenie using AWS Lambda
Amazon DevOps Guru directly integrates with Amazon EventBridge to notify you of events relating to generated insights and updates to insights. To begin routing these notifications to Opsgenie, you can configure routing rules to determine where to send notifications. As outlined below, you can also use pre-defined DevOps Guru patterns to only send notifications or trigger actions that match that pattern. You can select any of the following pre-defined patterns to filter events to trigger actions in a supported AWS resource. Here are the following predefined patterns supported by DevOps Guru:
DevOps Guru New Insight Open
DevOps Guru New Anomaly Association
DevOps Guru Insight Severity Upgraded
DevOps Guru New Recommendation Created
DevOps Guru Insight Closed
By default, the patterns referenced above are enabled so we will leave all patterns operational in this implementation. However, you do have flexibility to change which of these patterns to choose to send to Opsgenie. When EventBridge receives an event, the EventBridge rule matches incoming events and sends it to a target, such as AWS Lambda, to process and send the insight to Opsgenie.
Prerequisites
The following prerequisites are required for this walkthrough:
In this step, you will navigate to Opsgenie to create the integration with DevOps Guru and to obtain the API key and team name within your account. These parameters will be used as inputs in a later section of this blog.
Navigate to Teams, and take note of the team name you have as shown below, as you will need this parameter in a later section.
Figure 2: Opsgenie team names
Click on the team to proceed and navigate to Integrations on the left-hand pane. Click on Add Integration and select the Amazon DevOps Guru option.
Figure 3: Integration option for DevOps Guru
Now, scroll down and take note of the API Key for this integration and copy it to your notes as it will be needed in a later section. Click Save Integration at the bottom of the page to proceed.
Figure 4: API Key for DevOps Guru Integration
Now, the Opsgenie integration has been created and we’ve obtained the API key and team name. The email of any team member will be used in the next section as well.
Review & launch the AWS SAM template to deploy the solution
In this step, you will review & launch the SAM template. The template will deploy an AWS Lambda function that is triggered by an Amazon EventBridge rule when Amazon DevOps Guru generates a new event. The Lambda function will retrieve the parameters obtained from the deployment and pushes the events to Opsgenie via an API.
Reviewing the template
Below is the SAM template that will be deployed in the next step. This template launches a few key components specified earlier in the blog. The Transform section of the template allows us takes an entire template written in the AWS Serverless Application Model (AWS SAM) syntax and transforms and expands it into a compliant CloudFormation template. Under the Resources section this solution will deploy an AWS Lamba function using the Java runtime as well as an Amazon EventBridge Rule/Pattern. Another key aspect of the template are the Parameters. As shown below, the ApiKey, Email, and TeamName are parameters we will use for this CloudFormation template which will then be used as environment variables for our Lambda function to pass to OpsGenie.
Figure 5: Review of SAM Template
Launching the Template
Navigate to the directory of choice within a terminal and clone the GitHub repository with the following command:
Change directories with the command below to navigate to the directory of the SAM template.
cd amazon-devops-guru-connector-opsgenie/OpsGenieServerlessTemplate
From the CLI, use the AWS SAM to build and process your AWS SAM template file, application code, and any applicable language-specific files and dependencies.
sam build
From the CLI, use the AWS SAM to deploy the AWS resources for the pattern as specified in the template.yml file.
sam deploy --guided
You will now be prompted to enter the following information below. Use the information obtained from the previous section to enter the Parameter ApiKey, Parameter Email, and Parameter TeamName fields.
Stack Name
AWS Region
Parameter ApiKey
Parameter Email
Parameter TeamName
Allow SAM CLI IAM Role Creation
Test the solution
Follow this blog to enable DevOps Guru and generate an operational insight.
When DevOps Guru detects a new insight, it will generate an event in EventBridge. EventBridge then triggers Lambda and sends the event to Opsgenie as shown below.
Figure 6: Event Published to Opsgenie with details such as the source, alert type, insight type, and a URL to the insight in the AWS console.enecccdgruicnuelinbbbigebgtfcgdjknrjnjfglclt
Cleaning up
To avoid incurring future charges, delete the resources.
From the command line, use AWS SAM to delete the serverless application along with its dependencies.
sam delete
Customizing Insights published using Amazon EventBridge & AWS Lambda
The foundation of the DevOps Guru and Opsgenie integration is based on Amazon EventBridge and AWS Lambda which allows you the flexibility to implement several customizations. An example of this would be the ability to generate an Opsgenie alert when a DevOps Guru insight severity is high. Another example would be the ability to forward appropriate notifications to the AIOps team when there is a serverless-related resource issue or forwarding a database-related resource issue to your DBA team. This section will walk you through how these customizations can be done.
EventBridge customization
EventBridge rules can be used to select specific events by using event patterns. As detailed below, you can trigger the lambda function only if a new insight is opened and the severity is high. The advantage of this kind of customization is that the Lambda function will only be invoked when needed.
Open the file template.yaml reviewed in the previous section and implement the changes as highlighted below under the Events section within resources (original file on the left, changes on the right hand side).
Figure 7: CloudFormation template file changed so that the EventBridge rule is only triggered when the alert type is “DevOps Guru New Insight Open” and insightSeverity is “high”.
Save the changes and use the following command to apply the changes
sam deploy --template-file template.yaml
Accept the changeset deployment
Determining the Ops team based on the resource type
Another customization would be to change the Lambda code to route and control how alerts will be managed. Let’s say you want to get your DBA team involved whenever DevOps Guru raises an insight related to an Amazon RDS resource. You can change the AlertType Java class as follows:
To begin this customization of the Lambda code, the following changes need to be made within the AlertType.java file:
At the beginning of the file, the standard java.util.List and java.util.ArrayList packages were imported
Line 60: created a list of CloudWatch metrics namespaces
Line 74: Assigned the dataIdentifiers JsonNode to the variable dataIdentifiersNode
Line 75: Assigned the namespace JsonNode to a variable namespaceNode
Line 77: Added the namespace to the list for each DevOps Insight which is always raised as an EventBridge event with the structure detail►anomalies►0►sourceDetails►0►dataIdentifiers►namespace
Line 88: Assigned the default responder team to the variable defaultResponderTeam
Line 89: Created the list of responders and assigned it to the variable respondersTeam
Line 92: Check if there is at least one AWS/RDS namespace
Line 93: Assigned the DBAOps_Team to the variable dbaopsTeam
Line 93: Included the DBAOps_Team team as part of the responders list
Line 97: Set the OpsGenie request teams to be the responders list
Figure 8: java.util.List and java.util.ArrayList packages were imported
Figure 9: AlertType Java class customized to include DBAOps_Team for RDS-related DevOps Guru insights.
You then need to generate the jar file by using the mvn clean package command.
As result, the DBAOps_Team will be assigned to the Opsgenie alert in the case a DevOps Guru Insight is related to RDS.
Figure 10: Opsgenie alert assigned to both DBAOps_Team and AIOps_Team.
Conclusion
In this post, you learned how Amazon DevOps Guru integrates with Amazon EventBridge and publishes insights to Opsgenie using AWS Lambda. By creating an Opsgenie integration with DevOps Guru, you can now leverage Opsgenie strengths, incident management, team communication, and collaboration when responding to an insight. All of the insight data can be viewed and addressed in Opsgenie’s Incident Command Center (ICC). By customizing the data sent to Opsgenie via Lambda, you can empower your organization even more by fine tuning and displaying the most relevant data thus decreasing the MTTR (mean time to resolve) of the responding operations team.
AWS WAF is a web application firewall service that helps you protect your applications from common exploits that could affect your application’s availability and your security posture. One of the most useful ways to detect and respond to malicious web activity is to collect and analyze AWS WAF logs. You can perform this task conveniently by sending your AWS WAF logs to Amazon CloudWatch Logs and visualizing them through an Amazon CloudWatch dashboard.
This blog post builds on the concepts introduced in the blog post Analyzing AWS WAF Logs in Amazon CloudWatch Logs. There we introduced how to natively set up AWS WAF logging to Amazon CloudWatch logs, and discussed the basic options that are available for visualizing and analyzing the data provided in the logs.
The only AWS services that you need to turn on for this solution are Amazon CloudWatch and AWS WAF. The solution assumes that you’ve previously set up AWS WAF log delivery to Amazon CloudWatch Logs. If you have not done so, follow the instructions for AWS WAF logging destinations – CloudWatch Logs.
You will need to provide the following parameters for the CloudFormation template:
CloudWatch log group name for the AWS WAF logs
The AWS Region for the logs
The name of the AWS WAF web access control list (web ACL)
Solution overview
The architecture of the solution is outlined in Figure 1. The solution takes advantage of the native integration available between AWS WAF and CloudWatch, which simplifies the setup and management of this solution.
Figure 1: Solution architecture
In the solution, the logs are sent to CloudWatch (when you enable log delivery). From there, they’re ready to be consumed by all the different service options that CloudWatch offers, including the ones that we’ll use in this solution: CloudWatch Logs Insights and Contributor Insights.
Deploy the solution
Choose the following Launch stack button to launch the CloudFormation stack in your account.
You’ll be redirected to the CloudFormation service in the AWS US East (N. Virginia) Region, which is the default Region to deploy this solution, although this can vary depending on where your web ACL is located. You can change the Region as preferred. The template will spin up multiple cloud resources, such as the following:
CloudWatch Logs Insights queries
CloudWatch Contributor Insights visuals
CloudWatch dashboard
The solution is quickly deployed to your account and is ready to use in less than 30 minutes. You can use the solution when the status of the stack changes to CREATE_COMPLETE.
As a measure to control costs, you can also choose whether to create the Contributor Insights rules and enable them by default. For more information on costs, see the Cost considerations section later in this post.
Explore and validate the dashboard
When the CloudFormation stack is complete, you can choose the Output tab in the CloudFormation console and then choose the dashboard link. This will take you to the CloudWatch service in the AWS Management Console. The dashboard time range presents information for the last hour of activity by default, and can go up to one week, but keep in mind that Contributor Insights has a maximum time range of 24 hours. You can also select a different dashboard refresh interval from 10 seconds up to 15 minutes.
The dashboard provides the following information from CloudWatch.
Rule name
Description
WAF_top_terminating_rules
This rule shows the top rules where the requests are being terminated by AWS WAF. This can help you understand the main cause of blocked requests.
WAF_top_ips
This rule shows the top source IPs for requests. This can help you understand if the traffic and activity that you see is spread across many IPs or concentrated in a small group of IPs.
WAF_top_countries
This rule shows the main source countries for the IPs in the requests. This can help you visualize where the traffic is originating.
WAF_top_user_agents
This rule shows the main user agents that are being used to generate the requests. This will help you isolate problematic devices or identify potential false positives.
WAF_top_uri
This rule shows the main URIs in the requests that are being evaluated. This can help you identify if one specific path is the target of activity.
WAF_top_http
This rule shows the HTTP methods used for the requests examined by AWS WAF. This can help you understand the pattern of behavior of the traffic.
WAF_top_referrer_hosts
This rule shows the main referrer from which requests are being sent. This can help you identify incorrect or suspicious origins of requests based on the known application flow.
WAF_top_rate_rules
This rule shows the main rate rules being applied to traffic. It helps understand volumetric activity identified by AWS WAF.
WAF_top_labels
This rule shows the top labels found in logs. This can help you visualize the main rules that are matching on the requests evaluated by AWS WAF.
The dashboard also provides the following information from the default CloudWatch metrics sent by AWS WAF.
Rule name
Description
AllowedvsBlockedRequests
This metric shows the number of all blocked and allowed requests. This can help you understand the number of requests that AWS WAF is actively blocking.
Bot Requests vs non-Bot requests
This visual shows the number of requests identified as bots versus non-bots (if you’re using AWS WAF Bot Control).
All Requests
This metric shows the number of all requests, separated by bot and non-bot origin. This can help you understand all requests that AWS WAF is evaluating.
CountedRequests
This metric shows the number of all counted requests. This can help you understand the requests that are matching a rule but not being blocked, and aid the decision of a configuration change during the testing phase.
CaptchaRequests
This metric shows requests that go through the CAPTCHA rule.
Figure 2 shows an example of how the CloudWatch dashboard displays the data within this solution. You can rearrange and customize the elements within the dashboard as needed.
You can review each of the queries and rules deployed with this solution. You can also customize these baseline queries and rules to provide more detailed information or to add custom queries and rules to the solution code. For more information on how to build queries and use CloudWatch Logs and Contributor Insights, see the CloudWatch documentation.
Use the dashboard for monitoring
After you’ve set up the dashboard, you can monitor the activity of the sites that are protected by AWS WAF. If suspicious activity is reported, you can use the visuals to understand the traffic in more detail, and drive incident response actions as needed.
Let’s consider an example of how to use your new dashboard and its data to drive security operations decisions. Suppose that you have a website that sells custom clothing at a bargain price. It has a sign-up link to receive offers, and you’re getting reports of unusual activity by the application team. By looking at the metrics for the web ACL that protects the site, you can see the main country for source traffic and the contributing URIs, as shown in Figure 3. You can also see that most of the activity is being detected by rules that you have in place, so you can set the rules to block traffic, or if they are already blocking, you can just monitor the activity.
You can use the same visuals to decide whether an AWS WAF rule with high activity can be changed to autoblock suspicious web traffic without affecting valid customer traffic. By looking at the top terminating rules and cross-referencing information, such as source IPs, user agents, top URIs, and other request identifiers, you can understand the traffic pattern and activity of different applications and endpoints. From here, you can investigate further by using specific queries with CloudWatch Logs Insights.
Operational and security management with CloudWatch Logs Insights
You can use CloudWatch Logs Insights to interactively search and analyze log data in Amazon CloudWatch Logs using advanced queries to effectively investigate operational issues and security incidents.
Examine a bot reported as a false positive
You can use CloudWatch Logs Insights to identify requests that have specific labels to understand where the traffic is originating from based on source IP address and other essential event details. A simple example is investigating requests flagged as potential false positives.
Imagine that you have a reported false positive request that was flagged as a non-browser by AWS WAF Bot Control. You can run the non-browser user agent query that was created by the provided template on CloudWatch Logs Insights, as shown in the following example, and then verify the source IPs for the top hits for this rule group. Or you can look for a specific request that has been flagged as a false positive, in order to review the details and make adjustments as needed.
The non-browser user agent query also allows you confirm whether this request has other rule hits that were in count mode and were non-terminating; you can do this by examining the labels. If there are multiple rules matching the requests, that can be an indicator of suspicious activity.
If you have a CAPTCHA challenge configured on the endpoint, you can also look at CAPTCHA responses. The CaptchaTokenqueryDefinition query provided in this solution uses a variation of the preceding format, and can display the main IPs from which bad tokens are being sent. An example query is shown following, along with the query results in Figure 4. If you have signals from non-browser user agents and CAPTCHA tokens missing, then that is a strong indicator of suspicious activity.
fields@timestamp, httpRequest.clientIp
| filter captchaResponse.failureReason = "TOKEN_MISSING"
| statscount(*) as requestCount by httpRequest.clientIp, httpRequest.country
| sort requestCount desc
| limit10
Figure 4: Main IP addresses and number of counts for CAPTCHA responses
This information can provide an indication of the main source of activity. You can then use other visuals, like top user agents or top referrers, to provide more context to the information and inform further actions, such as adding new rules to the AWS WAF configuration.
You can adapt the queries provided in the sample solution to other use cases by using the fields provided in the left-hand pane of CloudWatch Logs Insights.
Cost considerations
Configuring AWS WAF to send logs to Amazon CloudWatch logs doesn’t have an additional cost. The cost incurred is for the use of the CloudWatch features and services, such as log storage and retention, Contributor Insights rules enabled, Logs Insights queries run, matched log events, and CloudWatch dashboards. For detailed information on the pricing of these features, see the CloudWatch Logs pricing information. You can also get an estimate of potential costs by using the AWS pricing calculator for CloudWatch.
One way to help offset the cost of CloudWatch features and services is to restrict the use of the dashboard and enforce a log retention policy for AWS WAF that makes it cost effective. If you use the queries and monitoring only as-needed, this can also help reduce costs. By limiting the running of queries and the matched log events for the Contributor Insights rules, you can enable the rules only when you need them. AWS WAF also provides the option to filter the logs that are sent when logging is enabled. For more information, see AWS WAF log filtering.
Conclusion
In this post, you learned how to use a pre-built CloudWatch dashboard to monitor AWS WAF activity by using metrics and Contributor Insights rules. The dashboard can help you identify traffic patterns and activity, and you can use the sample Logs Insights queries to explore the log information in more detail and examine false positives and suspicious activity, for rule tuning.
For more information on AWS WAF and the features mentioned in this post, see the AWS WAF documentation.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on AWS WAF re:Post.
Want more AWS Security news? Follow us on Twitter.
January 25, 2023: We updated this post to reflect the fact that CloudHSM SDK3 does not support serverless environments and we strongly recommend deploying SDK5.
AWS CloudHSM provides hardware security modules (HSMs) in the AWS Cloud. With CloudHSM, you can generate and use your own encryption keys in the AWS Cloud, and manage your keys by using FIPS 140-2 Level 3 validated HSMs. Your HSMs are part of a CloudHSM cluster. CloudHSM automatically manages synchronization, high availability, and failover within a cluster.
CloudHSM is part of the AWS Cryptography suite of services, which also includes AWS Key Management Service (AWS KMS), AWS Secrets Manager, and AWS Private Certificate Authority (AWS Private CA). AWS KMS, Secrets Manager, and AWS Private CA are fully managed services that are convenient to use and integrate. You’ll generally use CloudHSM only if your workload requires single-tenant HSMs under your own control, or if you need cryptographic algorithms or interfaces that aren’t available in the fully managed alternatives.
This solution demonstrates how to create a Docker container that uses the CloudHSM JCE SDK to generate a key and use it to encrypt and decrypt data.
Note: In this example, you must manually enter the crypto user (CU) credentials as environment variables when you run the container. For production workloads, you’ll need to consider how to secure and automate the handling and distribution of these credentials. You should work with your security or compliance officer to ensure that you’re using an appropriate method of securing HSM login credentials. For more information on securing credentials, see AWS Secrets Manager.
Figure 1 shows the solution architecture. The Java application, running in a Docker container, integrates with JCE and communicates with CloudHSM instances in a CloudHSM cluster through HSM elastic network interfaces (ENIs). The Docker container runs in an EC2 instance, and access to the HSM ENIs is controlled with a security group.
Figure 1: Architecture diagram
Prerequisites
To implement this solution, you need to have working knowledge of the following items:
CloudHSM
Docker 20.10.17 – used at the time of this post
Java 8 or Java 11 – supported at the time of this post
Maven 3.05 – used at the time of this post
Here’s what you’ll need to follow along with my example:
An active CloudHSM cluster with at least one active HSM instance. You can follow the CloudHSM getting started guide to create, initialize, and activate a CloudHSM cluster.
Note: For a production cluster, you should have at least two active HSM instances spread across Availability Zones in the Region.
An Amazon Linux 2 EC2 instance in the same virtual private cloud (VPC) in which you created your CloudHSM cluster. The Amazon Elastic Compute Cloud (Amazon EC2) instance must have the CloudHSM cluster security group attached—this security group is automatically created during the cluster initialization and is used to control network access to the HSMs. To learn about attaching security groups to allow EC2 instances to connect to your HSMs, see Create a cluster in the AWS CloudHSM User Guide.
In this section, I’ll walk you through how to download, configure, compile, and run a solution in Docker.
To set up Docker and run the application that encrypts and decrypts data with a key in AWS CloudHSM
On your Amazon Linux EC2 instance, install Docker by running the following command.
# sudo yum -y install docker
Start the docker service.
# sudo service docker start
Create a new directory and move to it. In my example, I use a directory named cloudhsm_container. You’ll use the new directory to configure the Docker image.
 # mkdir cloudhsm_container
 # cd cloudhsm_container
Copy the CloudHSM cluster’s trust anchor certificate (customerCA.crt) to the directory that you just created. You can find the trust anchor certificate on a working CloudHSM client instance under the path /opt/cloudhsm/etc/customerCA.crt. The certificate is created during initialization of the CloudHSM cluster and is required to connect to the CloudHSM cluster. This enables our application to validate that the certificate presented by the CloudHSM cluster was signed by our trust anchor certificate.
In your new directory (cloudhsm_container), create a new file with the name run_sample.sh that includes the following contents. The script runs the Java class that is used to generate an Advanced Encryption Standard (AES) key to encrypt and decrypt your data.
In the new directory, create another new file and name it Dockerfile (with no extension). This file will specify that the Docker image is built with the following components:
The CloudHSM client package.
The CloudHSM Java JCE package.
OpenJDK 1.8 (Java 8). This is needed to compile and run the Java classes and JAR files.
Maven, a build automation tool that is needed to assist with building the Java classes and JAR files.
Cut and paste the following contents into Dockerfile.
Note: You will need to customize your Dockerfile, as follows:
Make sure to specify the SDK version to replace the one specified in the pom.xml file in the sample code. As of the writing of this post, the most current version is 5.7.0. To find the SDK version, follow the steps in the topic Check your client SDK version. For more information, see the Building section in the README file for the Cloud HSM JCE examples.
Make sure to update the HSM_IP line with the IP of an HSM in your CloudHSM cluster. You can get your HSM IPs from the CloudHSM console, or by running the describe-clusters AWS CLI command.
	# Use the amazon linux image
	FROM amazonlinux:2

	# Pass HSM IP address as a build argument
	ARG HSM_IP

	# Install CloudHSM client
	RUN yum install -y https://s3.amazonaws.com/cloudhsmv2-software/CloudHsmClient/EL7/cloudhsm-jce-latest.el7.x86_64.rpm

	# Install Java, Maven, wget, unzip and ncurses-compat-libs
	RUN yum install -y java maven wget unzip ncurses-compat-libs

	# Create a work dir
	WORKDIR /app

	# Download sample code
	RUN wget https://github.com/aws-samples/aws-cloudhsm-jce-examples/archive/refs/heads/sdk5.zip

	# unzip sample code
	RUN unzip sdk5.zip

	# Change to the create directory
	WORKDIR aws-cloudhsm-jce-examples-sdk5

# Build JAR files using the installed CloudHSM JCE Provider version
RUN export CLOUDHSM_CLIENT_VERSION=`rpm -qi cloudhsm-jce | awk -F': ' '/Version/ {print $2}'` \
        && mvn validate -DcloudhsmVersion=$CLOUDHSM_CLIENT_VERSION \
        && mvn clean package -DcloudhsmVersion=$CLOUDHSM_CLIENT_VERSION

  # Configure cloudhsm-client
  COPY customerCA.crt /opt/cloudhsm/etc/
  RUN /opt/cloudhsm/bin/configure-jce -a $HSM_IP

  # Copy the run_sample.sh script
  COPY run_sample.sh .

  # Run the script
  CMD ["bash","run_sample.sh"]
Now you’re ready to build the Docker image. Run the following command, with the name jce_sample. This command will let you use the Dockerfile that you created in step 6 to create the image.
To run a Docker container from the Docker image that you just created, run the following command. Make sure to replace the user and password with your actual CU username and password. (If you need help setting up your CU credentials, see prerequisite 3. For more information on how to provide CU credentials to the AWS CloudHSM Java JCE Library, see Providing credentials to the JCE provider in the CloudHSM User Guide).
# sudo docker run --env HSM_USER=<user> --env HSM_PASSWORD=<password> jce_sample
This solution provides an example of how to run CloudHSM client workloads in Docker containers. You can use the solution as a reference to implement your cryptographic application in a way that benefits from the high availability and load balancing built in to CloudHSM without compromising the flexibility that Docker provides for developing, deploying, and running applications.
If you have comments about this post, submit them in the Comments section below.
Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.
Uncovering the root cause of an Amazon GuardDuty finding can be a complex task, requiring security operations center (SOC) analysts to collect a variety of logs, correlate information across logs, and determine the full scope of affected resources.
Sometimes you need to do this type of in-depth analysis because investigating individual security findings in insolation doesn’t always capture the full impact of affected resources.
With Amazon Detective, you can analyze and visualize various logs and relationships between AWS entities to streamline your investigation. In this post, you will learn how to use a feature of Detective—finding groups—to simplify and expedite the investigation of a GuardDuty finding.
Detective uses machine learning, statistical analysis, and graph theory to generate visualizations that help you to conduct faster and more efficient security investigations. The finding groups feature reduces triage time and provides a clear view of related GuardDuty findings. With finding groups, you can investigate entities and security findings that might have been overlooked in isolation. Finding groups also map GuardDuty findings and their relevant tactics, techniques, and procedures to the MITRE ATT&CK framework. By using MITRE ATT&CK, you can better understand the event lifecycle of a finding group.
Finding groups are automatically enabled for both existing and new customers in AWS Regions that support Detective. There is no additional charge for finding groups. If you don’t currently use Detective, you can start a free 30-day trial.
Use finding groups to simplify an investigation
Because finding groups are enabled by default, you start your investigation by simply navigating to the Detective console. You will see these finding groups in two different places: the Summary and the Finding groups pages. On the Finding groups overview page, you can also use the search capability to look for collected metadata for finding groups, such as severity, title, finding group ID, observed tactics, AWS accounts, entities, finding ID, and status. The entities information can help you narrow down finding groups that are more relevant for specific workloads.
Figure 1 shows the finding groups area on the Summary page in the Amazon Detective console, which provides high-level information on some of the individual finding groups.
Figure 1: Detective console summary page
Figure 2 shows the Finding groups overview page, with a list of finding groups filtered by status. The finding group shown has a status of Active.
Figure 2: Detective console finding groups overview page
You can choose the finding group title to see details like the severity of the finding group, the status, scope time, parent or child finding groups, and the observed tactics from the MITRE ATT&CK framework. Figure 3 shows a specific finding group details page.
Figure 3: Detective console showing a specific finding group details page
Below the finding group details, you can review the entities and associated findings for this finding group, as shown in Figure 4. From the Involved entities tab, you can pivot to the entity profile pages for more details about that entity’s behavior. From the Involved findings tab, you can select a finding to review the details pane.
Figure 4: Detective console showing involved entities of a finding group
In Figure 4, the search functionality on the Involved entities tab is being used to look at involved entities that are of type AWS role or EC2 instance. With such a search filter in Detective, you have more data in a single place to understand which Amazon Elastic Compute Cloud (Amazon EC2) instances and AWS Identity and Access Management (IAM) roles were involved in the GuardDuty finding and what findings were associated with each entity. You can also select these different entities to see more details. With finding groups, you no longer have to craft specific log searches or search for the AWS resources and entities that you should investigate. Detective has done this correlation for you, which reduces the triage time and provides a more comprehensive investigation.
With the release of finding groups, Detective infers relationships between findings and groups them together, providing a more convenient starting point for investigations. Detective has evolved from helping you determine which resources are related to a single entity (for example, what EC2 instances are communicating with a malicious IP), to correlating multiple related findings together and showing what MITRE tactics are aligned across those findings, helping you better understand a more advanced single security event.
Conclusion
In this blog post, we showed how you can use Detective finding groups to simplify security investigations through grouping related GuardDuty findings and AWS entities, which provides a more comprehensive view of the lifecycle of the potential security incident. Finding groups are automatically enabled for both existing and new customers in AWS Regions that support Detective. There is no additional charge for finding groups. If you don’t currently use Detective, you can start a free 30-day trial. For more information on finding groups, see Analyzing finding groups in the Amazon Detective User Guide.
If you have feedback about this post, submit comments in the Comments section below. You can also start a new thread on the Amazon Detective re:Post or contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
Serverless applications are a modernized way to perform analytics among business departments and engineering teams. Business teams can gain meaningful insights by simplifying their reporting through web applications and distributing it to a broader audience.
Use cases can include the following:
Dashboarding – A webpage consisting of tables and charts where each component can offer insights to a specific business department.
Reporting and analysis – An application where you can trigger large analytical queries with dynamic inputs and then view or download the results.
Management systems – An application that provides a holistic view of the internal company resources and systems.
ETL workflows – A webpage where internal company individuals can trigger specific extract, transform, and load (ETL) workloads in a user-friendly environment with dynamic inputs.
Data abstraction – Decouple and refactor underlying data structure and infrastructure.
Ease of use – An application where you want to give a large set of user-controlled access to analytics without having to onboard each user to a technical platform. Query updates can be completed in an organized manner and maintenance has minimal overhead.
In this post, you will learn how to build a serverless analytics application using Amazon Redshift Data API and Amazon API Gateway WebSocket and REST APIs.
Amazon Redshift is fully managed by AWS, so you no longer need to worry about data warehouse management tasks such as hardware provisioning, software patching, setup, configuration, monitoring nodes and drives to recover from failures, or backups. The Data API simplifies access to Amazon Redshift because you don’t need to configure drivers and manage database connections. Instead, you can run SQL commands to an Amazon Redshift cluster by simply calling a secured API endpoint provided by the Data API. The Data API takes care of managing database connections and buffering data. The Data API is asynchronous, so you can retrieve your results later.
API Gateway is a fully managed service that makes it easy for developers to publish, maintain, monitor, and secure APIs at any scale. With API Gateway, you can create RESTful APIs and WebSocket APIs that enable real-time two-way communication applications. API Gateway supports containerized and serverless workloads, as well as web applications. API Gateway acts as a reverse proxy to many of the compute resources that AWS offers.
Event-driven model
Event-driven applications are increasingly popular among customers. Analytical reporting web applications can be implemented through an event-driven model. The applications run in response to events such as user actions and unpredictable query events. Decoupling the producer and consumer processes allows greater flexibility in application design and building decoupled processes. This design can be achieved with the Data API and API Gateway WebSocket and REST APIs.
Both REST API calls and WebSocket establish communication between the client and the backend. Due to the popularity of REST, you may wonder why WebSockets are present and how they contribute to an event-driven design.
What are WebSockets and why do we need them?
Unidirectional communication is customary when building analytical web solutions. In traditional environments, the client initiates a REST API call to run a query on the backend and either synchronously or asynchronously waits for the query to complete. The “wait” aspect is engineered to apply the concept of polling. Polling in this context is when the client doesn’t know when a backend process will complete. Therefore, the client will consistently make a request to the backend and check.
What is the problem with polling? Main challenges include the following:
Increased traffic in your network bandwidth – A large number of users performing empty checks will impact your backend resources and doesn’t scale well.
Cost usage – Empty requests don’t deliver any value to the business. You pay for the unnecessary cost of resources.
Delayed response – Polling is scheduled in time intervals. If the query is complete in-between these intervals, the user can only see the results after the next check. This delay impacts the user experience and, in some cases, may result in UI deadlocks.
WebSockets is another approach compared to REST when establishing communication between the front end and backend. WebSockets enable you to create a full duplex communication channel between the client and the server. In this bidirectional scenario, the client can make a request to the server and is notified when the process is complete. The connection remains open, with minimal network overhead, until the response is received.
You may wonder why REST is present, since you can transfer response data with WebSockets. A WebSocket is a light weight protocol designed for real-time messaging between systems. The protocol is not designed for handling large analytical query data and in API Gateway, each frame’s payload can only hold up to 32 KB. Therefore, the REST API performs large data retrieval.
By using the Data API and API Gateway, you can build decoupled event-driven web applications for your data analytical needs. You can create WebSocket APIs with API Gateway and establish a connection between the client and your backend services. You can then initiate requests to perform analytical queries with the Data API. Due to the Data API’s asynchronous nature, the query completion generates an event to notify the client through the WebSocket channel. The client can decide to either retrieve the query results through a REST API call or perform other follow-up actions. The event-driven architecture enables bidirectional interoperable messages and data while keeping your system components agnostic.
Solution overview
In this post, we show how to create a serverless event-driven web application by querying with the Data API in the backend, establishing a bidirectional communication channel between the user and the backend with the WebSocket feature in API Gateway, and retrieving the results using its REST API feature. Instead of designing an application with long-running API calls, you can use the Data API. The Data API allows you to run SQL queries asynchronously, removing the need to hold long, persistent database connections.
The web application is protected using Amazon Cognito, which is used to authenticate the users before they can utilize the web app and also authorize the REST API calls when made from the application.
Other relevant AWS services in this solution include AWS Lambda and Amazon EventBridge. Lambda is a serverless, event-driven compute resource that enables you to run code without provisioning or managing servers. EventBridge is a serverless event bus allowing you to build event-driven applications.
The solution creates a lightweight WebSocket connection between the browser and the backend. When a user submits a request using WebSockets to the backend, a query is submitted to the Data API. When the query is complete, the Data API sends an event notification to EventBridge. EventBridge signals the system that the data is available and notifies the client. Afterwards, a REST API call is performed to retrieve the query results for the client to view.
We have published this solution on the AWS Samples GitHub repository and will be referencing it during the rest of this post.
The following architecture diagram highlights the end-to-end solution, which you can provision automatically with AWS CloudFormation templates run as part of the shell script with some parameter variables.
The application performs the following steps (note the corresponding numbered steps in the process flow):
A web application is provisioned on AWS Amplify; the user needs to sign up first by providing their email and a password to access the site.
The user verifies their credentials using a pin sent to their email. This step is mandatory for the user to then log in to the application and continue access to the other features of the application.
After the user is signed up and verified, they can sign in to the application and requests data through their web or mobile clients with input parameters. This initiates a WebSocket connection in API Gateway. (Flow 1, 2)
The connection request is handled by a Lambda function, OnConnect, which initiates an asynchronous database query in Amazon Redshift using the Data API. The SQL query is taken from a SQL script in Amazon Simple Storage Service (Amazon S3) with dynamic input from the client. (Flow 3, 4, 6, 7)
In addition, the OnConnect Lambda function stores the connection, statement identifier, and topic name in an Amazon DynamoDB database. The topic name is an extra parameter that can be used if users want to implement multiple reports on the same webpage. This allows the front end to map responses to the correct report. (Flow 3, 4, 5)
The Data API runs the query, mentioned in step 2. When the operation is complete, an event notification is sent to EventBridge. (Flow 8)
EventBridge activates an event rule to redirect that event to another Lambda function, SendMessage. (Flow 9)
The SendMessage function notifies the client that the SQL query is complete via API Gateway. (Flow 10, 11, 12)
After the notification is received, the client performs a REST API call (GET) to fetch the results. (Flow 13, 14, 15, 16)
The GetResult function is triggered, which retrieves the SQL query result and returns it to the client.
The user is now able to view the results on the webpage.
When clients disconnect from their browser, API Gateway automatically deletes the connection information from the DynamoDB table using the onDisconnect function. (Flow 17, 18,19)
Prerequisites
Prior to deploying your event-driven web application, ensure you have the following:
An Amazon Redshift cluster in your AWS environment – This is your backend data warehousing solution to run your analytical queries. For instructions to create your Amazon Redshift cluster, refer to Getting started with Amazon Redshift.
After you create your Amazon Redshift cluster, add the AmazonS3ReadOnlyAccess permission to the associated cluster AWS Identity and Access Management (IAM) role.
An S3 bucket that you have access to – The S3 bucket will be your object storage solution where you can store your SQL scripts. To create your S3 bucket, refer to Create your first S3 bucket.
Deploy CloudFormation templates
The code associated to the design is available in the following GitHub repository. You can clone the repository inside an AWS Cloud9 environment in our AWS account. The AWS Cloud9 environment comes with AWS Command Line Interface (AWS CLI) installed, which is used to run the CloudFormation templates to set up the AWS infrastructure. Make sure that the jQuery library is installed; we use it to parse the JSON output during the run of the script.
The complete architecture is set up using three CloudFormation templates:
cognito-setup.yaml – Creates the Amazon Cognito user pool to web app client, which is used for authentication and protecting the REST API
backend-setup.yaml – Creates all the required Lambda functions and the WebSocket and Rest APIs, and configures them on API Gateway
webapp-setup.yaml – Creates the web application hosting using Amplify to connect and communicate with the WebSocket and Rest APIs.
These CloudFormation templates are run using the script.sh shell script, which takes care of all the dependencies as required.
A generic template is provided for you to customize your own DDL SQL scripts as well as your own query SQL scripts. We have created sample scripts for you to follow along.
Upload the modified sample DDL script and the sample query script into a preexisting S3 bucket that you own, and note down the S3 URI path.
If you want to run your own customized version, modify the DDL and query script to fit your scenario.
Edit the script.sh file before you run it and set the values for the following parameters:
RedshiftClusterEndpoint (aws_redshift_cluster_ep) – Your Amazon Redshift cluster endpoint available on the AWS Management Console
DBUsername (aws_dbuser_name) – Your Amazon Redshift database user name
DDBTableName (aws_ddbtable_name) – The name of your DynamoDB table name that will be created
WebsocketEndpointSSMParameterName (aws_wsep_param_name) – The parameter name that stores the WebSocket endpoint in AWS Systems Manager Parameter Store.
RestApiEndpointSSMParameterName (aws_rapiep_param_name) – The parameter name that stores the REST API endpoint in Parameter Store.
DDLScriptS3Path (aws_ddl_script_path) – The S3 URI to the DDL script that you uploaded.
QueryScriptS3Path (aws_query_script_path) – The S3 URI to the query script that you uploaded.
AWSRegion (aws_region) – The Region where the AWS infrastructure is being set up.
CognitoPoolName (aws_user_pool_name) – The name you want to give to your Amazon Cognito user pool
ClientAppName (aws_client_app_name) – The name of the client app to be configured for the web app to handle the user authentication for the users
The default acceptable values are already provided as part of the downloaded code.
Run the script using the following command:
./script.sh
During deployment, AWS CloudFormation creates and triggers the Lambda function SetupRedshiftLambdaFunction, which sets up an Amazon Redshift database table and populates data into the table. The following diagram illustrates this process.
Use the demo app
When the shell script is complete, you can start interacting with the demo web app:
On the Amplify console, under All apps in the navigation pane, choose DemoApp.
Choose Run build.
The DemoApp web application goes through a phase of Provision, Build, Deploy.
When it’s complete, use the URL provided to access the web application.
The following screenshot shows the web application page. It has minimal functionality: you can sign in, sign up, or verify a user.
Choose Sign Up.
For Email ID, enter an email.
For Password, enter a password that is at least eight characters long, has at least one uppercase and lowercase letter, at least one number, and at least one special character.
Choose Let’s Enroll.
The Verify your Login to Demo App page opens.
Enter your email and the verification code sent to the email you specified.
Choose Verify.
You’re redirected to a login page.
Sign in using your credentials.
You’re redirected to the demoPage.html website.
Choose Open Connection.
You now have an active WebSocket connection between your browser and your backend AWS environment.
For Trip Month, specify a month (for this example, December) and choose Submit.
You have now defined the month and year you want to query your data upon. After a few seconds, you can to see the output delivered from the WebSocket.
You may continue using the active WebSocket connection for additional queries—just choose a different month and choose Submit again.
When you’re done, choose Close Connection to close the WebSocket connection.
For exploratory purposes, while your WebSocket connection is active, you can navigate to your DynamoDB table on the DynamoDB console to view the items that are currently stored. After the WebSocket connection is closed, the items stored in DynamoDB are deleted.
Clean up
To clean up your resources, complete the following steps:
On the Amazon S3 console, navigate to the S3 bucket containing the sample DDL script and query script and delete them from the bucket.
On the Amazon Redshift console, navigate to your Amazon Redshift cluster and delete the data you copied over from the sample DDL script.
Run truncate nyc_yellow_taxi;
Run drop table nyc_yellow_taxi;
On the AWS CloudFormation console, navigate to the CloudFormation stacks and choose Delete. Delete the stacks in the following order:
WebappSetup
BackendSetup
CognitoSetup
All resources created in this solution will be deleted.
Monitoring
You can monitor your event-driven web application events, user activity, and API usage with Amazon CloudWatch and AWS CloudTrail. Most areas of this solution already have logging enabled. To view your API Gateway logs, you can turn on CloudWatch Logs. Lambda comes with default logging and monitoring and can be accessed with CloudWatch.
Security
You can secure access to the application using Amazon Cognito, which is a developer-centric and cost-effective customer authentication, authorization, and user management solution. It provides both identity store and federation options that can scale easily. Amazon Cognito supports logins with social identity providers and SAML or OIDC-based identity providers, and supports various compliance standards. It operates on open identity standards (OAuth2.0, SAML 2.0, and OpenID Connect). You can also integrate it with API Gateway to authenticate and authorize the REST API calls either using the Amazon Cognito client app or a Lambda function.
Considerations
The nature of this application includes a front-end client initializing SQL queries to Amazon Redshift. An important component to consider are potential malicious activities that the client can perform, such as SQL injections. With the current implementation, that is not possible. In this solution, the SQL queries preexist in your AWS environment and are DQL statements (they don’t alter the data or structure). However, as you develop this application to fit your business, you should evaluate these areas of risk.
The AWS services that the CloudFormation templates provision in this solution are all serverless. In terms of cost optimization, you only pay for what you use. This model also allows you to scale without manual intervention. Review the following pages to determine the associated pricing for each service:
In this post, we showed you how to create an event-driven application using the Amazon Redshift Data API and API Gateway WebSocket and REST APIs. The solution helps you build data analytical web applications in an event-driven architecture, decouple your application, optimize long-running database queries processes, and avoid unnecessary polling requests between the client and the backend.
You also used severless technologies, API Gateway, Lambda, DynamoDB, and EventBridge. You didn’t have to manage or provision any servers throughout this process.
This event-driven, serverless architecture offers greater extensibility and simplicity, making it easier to maintain and release new features. Adding new components or third-party products is also simplified.
With the instructions in this post and the generic CloudFormation templates we provided, you can customize your own event-driven application tailored to your business. For feedback or contributions, we welcome you to contact us through the AWS Samples GitHub Repository by creating an issue.
About the Authors
David Zhang is an AWS Data Architect in Global Financial Services. He specializes in designing and implementing serverless analytics infrastructure, data management, ETL, and big data systems. He helps customers modernize their data platforms on AWS. David is also an active speaker and contributor to AWS conferences, technical content, and open-source initiatives. During his free time, he enjoys playing volleyball, tennis, and weightlifting. Feel free to connect with him on LinkedIn.
Manash Deb is a Software Development Manager in the AWS Directory Service team. With over 18 years of software dev experience, his passion is designing and delivering highly scalable, secure, zero-maintenance applications in the AWS identity and data analytics space. He loves mentoring and coaching others and to act as a catalyst and force multiplier, leading highly motivated engineering teams, and building large-scale distributed systems.
Pavan Kumar Vadupu Lakshman Manikya is an AWS Solutions Architect who helps customers design robust, scalable solutions across multiple industries. With a background in enterprise architecture and software development, Pavan has contributed in creating solutions to handle API security, API management, microservices, and geospatial information system use cases for his customers. He is passionate about learning new technologies and solving, automating, and simplifying customer problems using these solutions.
An Amazon CodeCatalyst Dev Environment is a cloud-based development environment that you can use in CodeCatalyst to quickly work on the code stored in the source repositories of your project. The project tools and application libraries included in your Dev Environment are defined by a devfile in the source repository of your project.
Introduction
In the previous CodeCatalyst post, Team Collaboration with Amazon CodeCatalyst, I focused on CodeCatalyst’s collaboration capabilities and how that related to The Unicorn Project’s main protaganist. At the beginning of Chapter 2, Maxine is struggling to configure her development environment. She is two days into her new job and still cannot build the application code. She has identified over 100 dependencies she is missing. The documentation is out of date and nobody seems to know where the dependencies are stored. I can sympathize with Maxine. In this post, I will focus on managing development environments to show how CodeCatalyst removes the burden of managing workload specific configurations and produces reliable on-demand development environments.
Prerequisites
If you would like to follow along with this walkthrough, you will need to:
Have an AWS account associated with your space and have the IAM role in that account. For more information about the role and role policy, see Creating a CodeCatalyst service role.
Walkthrough
As with the previous posts in our CodeCatalyst series, I am going to use the Modern Three-tier Web Application blueprint. Blueprints provide sample code and CI/CD workflows to help make getting started easier across different combinations of programming languages and architectures. To follow along, you can re-use a project you created previously, or you can refer to a previous post that walks through creating a project using the blueprint.
One of the most difficult aspects of my time spent as a developer was finding ways to quickly contribute to a new project. Whenever I found myself working on a new project, getting to the point where I could meaningfully contribute to a project’s code base was always more difficult than writing the actual code. A major contributor to this inefficiency, was the lack of process managing my local development environment. I will be exploring how CodeCatalyst can help solve this challenge. For this walkthrough, I want to add a new test that will allow local testing of Amazon DynamoDB. To achieve this, I will use a CodeCatalyst dev environment.
CodeCatalyst Dev Environments are managed cloud-based development environments that you can use to access and modify code stored in a source repository. You can launch a project specific dev environment that will automate check-out of your project’s repo or you can launch an empty environment to use for accessing third-party source providers. You can learn more about CodeCatalyst Dev Environments in the CodeCatalyst User Guide.
Figure 1. Creating a new Dev Environment
To begin, I navigate to the Dev Environments page under the Code section of the navigaiton menu. I then use the Create Dev Environment to launch my environment. For this post, I am using the AWS Cloud9 IDE, but you can follow along with the IDE you are most comfortable using. In the next screen, I select Work in New Branch and assign local_testing for the new branch name, and I am branching from main. I leave the remaining default options and Create.
Figure 2. Dev Environment Create Options
After waiting less than a minute, my IDE is ready in a new tab and I am ready to begin work. The first thing I see in my dev environment is an information window asking me if I want to navigate to the Dev Environment Settings. Because I need to enable local testing of Dynamodb, not only for myself, but other developers that will collaborate on this project, I need to update the project’s devfile. I select to navigate to the settings tab because I know that contains information on the project’s devfile and allows me to access the file to edit.
Figure 3. Toolkit Welcome Banner
Devfiles allow you to model a Dev Environment’s configuration and dependencies so that you can re-produce consisent Dev Environments and reduce the manual effort in setting up future environments. The tools and application libraries included in your Dev Environment are defined by the devfile in the source repository of your project. Since this project was created from a blueprint, there is one provided. For blank projects, a default CodeCatalyst devfile is created when you first launch an environment. To learn more about the devfile, see https://devfile.io.
In the settings tab, I find a link to the devfile that is configured. When I click the edit button, a new file tab launches and I can now make changes. I first add an env section to the container that hosts our dev environment. By adding an environment variable and value, anytime a new dev environment is created from this project’s repository, that value will be included. Next, I add a second container to the dev environment that will run DynamoDB locally. I can do this by adding a new container component. I use Amazon’s verified DynamoDB docker image for my environment. Attaching additional images allow you to extend the dev environment and include tools or services that can be made available locally. My updates are highlighted in the green sections below.
Figure 4. Example Devfile
I save my changes and navigate back to the Dev Environment Settings tab. I notice that my changes were automatically detected and I am prompted to restart my development environment for the changes to take effect. Modifications to the devfile requires a restart. You can restart a dev environment using the toolkit, or from the CodeCatalyst UI.
Figure 5. Dev Environment Settings
After waiting a few seconds for my dev environment to restart, I am ready to write my test. I use the IDE’s file explorer, expand the repo’s ./tests/unit folder, and create a new file named test_dynamodb.py. Using the IS_LOCAL environment variable I configured in the devfile, I can include a conditional in my test that sets the endpoint that Amazon’s python SDK ( Boto3 ) will use to connect to the Dynamodb service. This way, I can run tests locally before pushing my changes and still have tests complete successfully in my project’s workflow. My full test file is included below.
Figure 6. Dynamodb test file
Now that I have completed my changes to the dev environment using the devfile and added a test, I am ready to run my test locally to verify. I will use pytest to ensure the tests are passing before pushing any changes. From the repo’s root folder, I run the command pip install -r requirements-dev.txt. Once my dependencies are installed, I then issue the command pytest -k unit. All tests pass as I expect.
Figure 7. Pytest test results
Rather than manually installing my development dependencies in each environment, I could also use the devfile to include commands and automate the execution of those commands during the dev environment lifecycle events. You can refer to the links for commands and events for more information.
Finally, I am ready to push my changes back to my CodeCatalyst source repository. I use the git extension of Cloud9 to review my changes. After reviewing my changes are what I expect, I use the git extension to stage, commit, and push the new test file and the modified devfile so other collaborators can adopt the improvements I made.
Figure 8. Changes reviewed in CodeCatalyst Cloud9 git extension.
Cleanup
If you have been following along with this workflow, you should delete the resources you deployed so you do not continue to incur charges. First, delete the two stacks that CDK deployed using the AWS CloudFormation console in the AWS account you associated when you launched the blueprint. These stacks will have names like mysfitsXXXXXWebStack and mysfitsXXXXXAppStack. Second, delete the project from CodeCatalyst by navigating to Project settings and choosing Delete project.
Conclusion
In this post, you learned how CodeCatalyst provides configurable on-demand dev environments. You also learned how devfiles help you define a consistent experience for developing within a CodeCatalyst project. Please follow our DevOps blog channel as I continue to explore how CodeCatalyst solve Maxine’s and other builders’ challenges.
In this blog post, you’ll learn how you can use a Completely Automated Public Turing test to tell Computers and Humans Apart (CAPTCHA) with other AWS WAF controls as part of a layered approach to provide comprehensive protection against bot traffic. We’ll describe a workflow that tracks the number of incoming requests to a site’s store page. The workflow then limits those requests if they exceed a certain threshold. Requests from IP addresses that exceed the threshold will be presented a CAPTCHA challenge to prove that the requests are being made by a human.
Amazon Web Services (AWS) offers many tools and recommendations that companies can use as they face challenges with bot traffic on their websites. Web applications can be compromised through a variety of vectors, including cross-site scripting, SQL injection, path traversal, local file inclusion, and distributed denial-of-service (DDoS) attacks. AWS WAF offers managed rules that are designed to provide protection against common application vulnerabilities or other unwanted web traffic, without requiring you to write your own rules.
There are some web attacks like web scraping, credential stuffing, and layer 7 DDoS attempts conducted by bots (as well as by humans) that target sensitive areas of your website, such as your store page. A CAPTCHA mitigates undesirable traffic by requiring the visitor to complete challenges before they are allowed to access protected resources. You can implement CAPTCHA to help prevent unwanted activities. Last year, AWS introduced AWS WAF CAPTCHA, which allows customers to set up AWS WAF rules that require CAPTCHA challenges to be completed for common targets such as forms (for example, search forms).
Scenario
Consider an attack where the unauthorized user is attempting to overwhelm a site’s store page by repeatedly sending search requests for different items.
Assume that traffic visits a website that is hosted through Amazon CloudFront and attempts the above behavior on the /store URL. In this scenario, there is a rate-based rule in place that will track the number of requests coming in from each IP. This rate-based rule tracks the rate of requests for each originating IP address and invokes the rule action on IPs with rates that go over the limit. With CAPTCHA implemented as the rule action, excessive attempts to search within a 5-minute window will result in a CAPTCHA challenge being presented to the user. This workflow is shown in Figure 1.
Figure 1: User visits a store page and is evaluated by a rate-based rule
When a user solves a CAPTCHA challenge, AWS automatically generates and encrypts a token and sends it to the client as a cookie. The client requests aren’t challenged again until the token has expired. AWS WAF calculates token expiration by using the immunity time configuration. You can configure the immunity time in a web access control list (web ACL) CAPTCHA configuration and in the configuration for a rule’s action setting. When a user provides an incorrect answer to a CAPTCHA challenge, the challenge informs the user and loads a new puzzle. When the user solves the challenge, the challenge automatically submits the original web request, updated with the CAPTCHA token from the successful puzzle completion.
Walkthrough
This workflow will require an AWS WAF rule within a new or existing rule group or web ACL. The rule will define how web requests are inspected and the action to take.
To create an AWS WAF rate-based rule
Open the AWS WAF console and in the left navigation pane, choose Web ACLs.
Choose an existing web ACL, or choose Create web ACL at the top right to create a new web ACL.
Under Rules, choose Add rules, and then in the drop-down list, choose Add my own rules and rule groups.
For Rule type, choose Rule builder.
In the Rule builder section, for Name, enter your rule name. For Type, choose Rate-based rule.
In the Request rate details section, enter your rate limit (for example, 100). For IP address to use for rate limiting, choose Source IP address, and for Criteria to count requests toward rate limit, choose Only consider requests that match criteria in a rule statement.
For Count only the requests that match the following statement, choose Matches the statement from the drop-down list.
In the Statement section, for Inspect, choose URI path. For Match type , choose Contains string.
For String to match, enter the URI path of your web page (for example, /store).
In the Action section, choose CAPTCHA.
(Optional) For Immunity time, choose Set a custom immunity time for this rule, or keep the default value (300 seconds).
To finish, choose Add rule, and then choose Save to add the rule to your web ACL.
After you add the rule, go to the Rules tab of your web ACL and navigate to your rule. Confirm that the output resembles what is shown in Figure 2. You should have a rate-based rule with a scope-down statement that matches the store URI path you entered earlier, and the action should be set to CAPTCHA.
The following is the JSON for the CAPTCHA rule that you just created. You can use this to validate your configuration. You can also use this JSON in the rule builder while creating the rule.
After you complete this configuration, the rule will be invoked when an IP address unsuccessfully attempts to search the store at a rate that exceeds the threshold. This user will be presented with a CAPTCHA challenge, as shown in Figure 6. If the user is successful, they will be routed back to the store page. Otherwise, they will be served a new puzzle until it is solved.
Figure 3: CAPTCHA challenge presented to a request that exceeded the threshold
Implementing rate-based rules and CAPTCHA also allows you to track IP addresses, limit the number of invalid search attempts, and use the specific IP information available to you within sampled requests and AWS WAF logs to work to prevent that traffic from affecting your resources. Additionally, you have visibility into IPs addresses blocked by rate-based rules so that you can later add these addresses to a block list or create custom logic as needed to mitigate false positives.
Conclusion
In this blog post, you learned how to configure and deploy a CAPTCHA challenge with AWS WAF that checks for web requests that exceed a certain rate threshold and requires the client sending such requests to solve a challenge. Please note the additional charge for enabling CAPTCHA on your web ACL (pricing can be found here). Although CAPTCHA challenges are simple for humans to complete, they should be harder for common bots to complete with any meaningful rate of success. You can use a CAPTCHA challenge when a block action would stop too many legitimate requests, but letting all traffic through would result in unacceptably high levels of unwanted requests, such as from bots.
If you have feedback about this blog post, submit comments in the Comments section below. You can also start a new thread on AWS WAF re:Post to get answers from the community.
Want more AWS Security news? Follow us on Twitter.
In the last post, OfferUp modernized its DevOps platform with Amazon EKS and Flagger to accelerate time to market, we talked about hypergrowth and the technical challenges encountered by OfferUp in its existing DevOps platform. As a reminder, we presented how OfferUp modernized its DevOps platform with Amazon Elastic Kubernetes Service (Amazon EKS) and Flagger to gain developer’s velocity, automate faster deployment, and achieve lower cost of ownership.
In this post, we discuss the technical steps to build a DevOps platform that enables the progressive deployment of microservices on Amazon Managed Amazon EKS. Progressive delivery exposes a new version of the software incrementally to ingress traffic and continuously measures the success rate of the metrics before allowing all of the new traffics to a newer version of the software. Flagger is the Graduate project of Cloud Native Computing Foundations (CNCF) that enables progressive canary delivery, along with bule/green and A/B Testing, while measuring metrics like HTTP/gRPC request success rate and latency. Flagger shifts and routes traffic between app versions using a service mesh or an Ingress controller
We leverage Gloo Ingress Controller for traffic routing, Prometheus, Datadog, and Amazon CloudWatch for application metrics analysis and Slack to send notification. Flagger will post messages to slack when a deployment has been initialized, when a new revision has been detected, and if the canary analysis failed or succeeded.
Prerequisite steps to build the modern DevOps platform
You need an AWS Account and AWS Identity and Access Management (IAM) user to build the DevOps platform. If you don’t have an AWS account with Administrator access, then create one now by clicking here. Create an IAM user and assign admin role. You can build this platform in any AWS region however, I will you us-west-1 region throughout this post. You can use a laptop (Mac or Windows) or an Amazon Elastic Compute Cloud (AmazonEC2) instance as a client machine to install all of the necessary software to build the GitOps platform. For this post, I launched an Amazon EC2 instance (with Amazon Linux2 AMI) as the client and install all of the prerequisite software. You need the awscli, git, eksctl, kubectl, and helm applications to build the GitOps platform. Here are the prerequisite steps,
Create a named profile(eks-devops) with the config and credentials file:
aws configure --profile eks-devops
AWS Access Key ID [None]: xxxxxxxxxxxxxxxxxxxxxx
AWS Secret Access Key [None]: xxxxxxxxxxxxxxxxxx
Default region name [None]: us-west-1
Default output format [None]:
View and verify your current IAM profile:
export AWS_PROFILE=eks-devops
aws sts get-caller-identity
If the Amazon EC2 instance doesn’t have git preinstalled, then install git in your Amazon EC2 instance:
sudo yum update -y
sudo yum install git -y
Check git version
git version
Git clone the repo and download all of the prerequisite software in the home directory.
Amazon ECR is a fully-managed container registry that makes it easy for developers to share and deploy container images and artifacts. ecr setup.sh script will create a new Amazon ECR repository and also push the podinfo images (6.0.0, 6.0.1, 6.0.2, 6.1.0, 6.1.5 and 6.1.6) to the Amazon ECR. Run ecr-setup.sh script with the parameter, “ECR repository name” (e.g. ps-flagger-repository) and region (e.g. us-west-1)
Technical steps to build the modern DevOps platform
This post shows you how to use the Gloo Edge ingress controller and Flagger to automate canary releases for progressive deployment on the Amazon EKS cluster. Flagger requires a Kubernetes cluster v1.16 or newer and Gloo Edge ingress 1.6.0 or newer. This post will provide a step-by-step approach to install the Amazon EKS cluster with managed node group, Gloo Edge ingress controller, and Flagger for Gloo in the Amazon EKS cluster. Now that the cluster, metrics infrastructure, and Flagger are installed, we can install the sample application itself. We’ll use the standard Podinfo application used in the Flagger project and the accompanying loadtester tool. The Flagger “podinfo” backend service will be called by Gloo’s “VirtualService”, which is the root routing object for the Gloo Gateway. A virtual service describes the set of routes to match for a set of domains. We’ll automate the canary promotion, with the new image of the “podinfo” service, from version 6.0.0 to version 6.0.1. We’ll also create a scenario by injecting an error for automated canary rollback while deploying version 6.0.2.
Use myeks-cluster.yaml to create your Amazon EKS cluster with managed nodegroup. myeks-cluster.yaml deployment file has “cluster name” value as ps-eks-66, region value as us-west-1, availabilityZones as [us-west-1a, us-west-1b], Kubernetes version as 1.24, and nodegroup Amazon EC2 instance type as m5.2xlarge. You can change this value if you want to build the cluster in a separate region or availability zone.
Create a namespace “gloo-system” and Install Gloo with Helm Chart. Gloo Edge is an Envoy-based Kubernetes-native ingress controller to facilitate and secure application traffic.
[Optional] If you’re using Datadog as a monitoring tool, then deploy Datadog agents as a DaemonSet using the Datadog Helm chart. Replace RELEASE_NAME and DATADOG_API_KEY accordingly. If you aren’t using Datadog, then skip this step. For this post, we leverage the Prometheus open-source monitoring tool.
Integrate Amazon EKS/ K8s Cluster with the Datadog Dashboard – go to the Datadog Console and add the Kubernetes integration.
[Optional] If you’re using Slack communication tool and have admin access, then Flagger can be configured to send alerts to the Slack chat platform by integrating the Slack alerting system with Flagger. If you don’t have admin access in Slack, then skip this step.
Create a namespace “apps”, and applications and load testing service will be deployed into this namespace.
kubectl create ns apps
Create a deployment and a horizontal pod autoscaler for your custom application or service for which canary deployment will be done.
kubectl -n apps apply -k app
kubectl get deployment -A
kubectl get hpa -n apps
Deploy the load testing service to generate traffic during the canary analysis.
kubectl -n apps apply -k tester
kubectl get deployment -A
kubectl get svc -n apps
Use apps-vs.yaml to create a Gloo virtual service definition that references a route table that will be generated by Flagger.
kubectl apply -f ./apps-vs.yaml
kubectl get vs -n apps
[Optional] If you have your own domain name, then open apps-vs.yaml in vi editor and replace podinfo.example.com with your own domain name to run the app in that domain.
Use canary.yaml to create a canary custom resource. Review the service, analysis, and metrics sections of the canary.yaml file.
kubectl apply -f ./canary.yaml
After a couple of seconds, Flagger will create the canary objects. When the bootstrap finishes, Flagger will set the canary status to “Initialized”.
kubectl -n apps get canary podinfo
NAME STATUS WEIGHT LASTTRANSITIONTIME
podinfo Initialized 0 2023-xx-xxTxx:xx:xxZ
Gloo automatically creates an ELB. Once the load balancer is provisioned and health checks pass, we can find the sample application at the load balancer’s public address. Note down the ELB’s Public address:
kubectl get svc -n gloo-system --field-selector 'metadata.name==gateway-proxy' -o=jsonpath='{.items[0].status.loadBalancer.ingress[0].hostname}{"\n"}'
Validate if your application is running, and you’ll see an output with version 6.0.0.
curl <load balancer’s public address> -H "Host:podinfo.example.com"
Trigger progressive deployments and monitor the status
You can Trigger a canary deployment by updating the application container image from 6.0.0 to 6.01.
kubectl -n apps set image deployment/podinfo podinfod=<ECR URI>:6.0.1
Flagger detects that the deployment revision changed and starts a new rollout.
kubectl -n apps describe canary/podinfo
Monitor all canaries, as the promoted status condition can have one of the following statuses: initialized, Waiting, Progressing, Promoting, Finalizing, Succeeded, and Failed.
watch kubectl get canaries --all-namespaces
curl < load balancer’s public address> -H "Host:podinfo.example.com"
Once canary is completed, validate your application. You can see that the version of the application is changed from 6.0.0 to 6.0.1.
[Optional] Open podinfo application from the laptop browser
Find out both of the IP addresses associated with load balancer.
dig < load balancer’s public address >
Open /etc/hosts file in the laptop and add both of the IPs of load balancer in the host file.
sudo vi /etc/hosts
<Public IP address of LB Target node> podinfo.example.com
e.g.
xx.xx.xxx.xxx podinfo.example.com
xx.xx.xxx.xxx podinfo.example.com
Type “podinfo.example.com” in your browser and you’ll find the application in form similar to this:
Figure 1: Greetings from podinfo v6.0.1
Automated rollback
While doing the canary analysis, you’ll generate HTTP 500 errors and high latency to check if Flagger pauses and rolls back the faulted version. Flagger performs automatic Rollback in the case of failure.
Introduce another canary deployment with podinfo image version 6.0.2 and monitor the status of the canary.
kubectl -n apps set image deployment/podinfo podinfod=<ECR URI>:6.0.2
Run HTTP 500 errors or a high-latency error from a separate terminal window.
Generate HTTP 500 errors:
watch curl -H 'Host:podinfo.example.com' <load balancer’s public address>/status/500
Generate high latency:
watch curl -H 'Host:podinfo.example.com' < load balancer’s public address >/delay/2
When the number of failed checks reaches the canary analysis threshold, the traffic is routed back to the primary, the canary is scaled to zero, and the rollout is marked as failed.
kubectl get canaries --all-namespaces
kubectl -n apps describe canary/podinfo
Cleanup
When you’re done experimenting, you can delete all of the resources created during this series to avoid any additional charges. Let’s walk through deleting all of the resources used.
Delete Amazon EKS Cluster After you’ve finished with the cluster and nodes that you created for this tutorial, you should clean up by deleting the cluster and nodes with the following command:
This post explained the process for setting up Amazon EKS cluster and how to leverage Flagger for progressive deployments along with Prometheus and Gloo Ingress Controller. You can enhance the deployments by integrating Flagger with Slack, Datadog, and webhook notifications for progressive deployments. Amazon EKS removes the undifferentiated heavy lifting of managing and updating the Kubernetes cluster. Managed node groups automate the provisioning and lifecycle management of worker nodes in an Amazon EKS cluster, which greatly simplifies operational activities such as new Kubernetes version deployments.
We encourage you to look into modernizing your DevOps platform from monolithic architecture to microservice-based architecture with Amazon EKS, and leverage Flagger with the right Ingress controller for secured and automated service releases.
Further Reading
Journey to adopt Cloud-Native DevOps platform Series #1: OfferUp modernized DevOps platform with Amazon EKS and Flagger to accelerate time to market
In modern data architectures, datasets are combined across an organization using a variety of purpose-built services to unlock insights. As a result, data governance becomes a key component for data consumers and producers to know that their data-driven decisions are based on trusted and accurate datasets. One aspect of data governance is data lineage, which captures the flow of data as it goes through various systems and allows consumers to understand how a dataset was derived.
In order to capture data lineage consistently across various analytical services, you need to use a common lineage model and a robust job orchestration that is able to tie together diverse data flows. One possible solution is the open-source OpenLineage project. It provides a technology-agnostic metadata model for capturing data lineage and integrates with widely used tools. For job orchestration, it integrates with Apache Airflow, which you can run on AWS conveniently through the managed service Amazon Managed Workflows for Apache Airflow (Amazon MWAA). OpenLineage provides a plugin for Apache Airflow that extracts data lineage from Directed Acyclic Graphs (DAGs).
In this post, we show how to get started with data lineage on AWS using OpenLineage. We provide a step-by-step configuration guide for the openlineage-airflow plugin on Amazon MWAA. Additionally, we share an AWS Cloud Development Kit (AWS CDK) project that deploys a pre-configured demo environment for evaluating and experiencing OpenLineage first-hand.
After staging and preparing source data from Amazon Simple Storage Service (Amazon S3), fact and dimension tables are eventually created. For this, Airflow orchestrates the execution of SQL statements that create and populate tables on Redshift Serverless.
The openlineage-airflow plugin collects metadata about creation of datasets and dependencies between them. This allows us to move from a jobs-centric approach of Airflow to a datasets-centric approach, improving the observability of workflows.
The following screenshot shows parts of the captured lineage for the previous example. It’s displayed in Marquez, an open-source metadata service for collection and visualization of data lineage with support for the OpenLineage standard. In Marquez, you can analyze the upstream datasets and transformations that eventually create the user dimension table on the right.
The example in this post is based on SQL and Amazon Redshift. OpenLineage also supports other transformation engines and data stores such as Apache Spark and dbt.
Solution overview
The following diagram shows the AWS setup required to capture data lineage using OpenLineage.
The workflow includes the following components:
The openlineage-airflow plugin is configured on Airflow as a lineage backend. Metadata about the DAG runs is passed by Airflow core to the plugin, which converts it into OpenLineage format and sends it to an external metadata store. In our demo setup, we use Marquez as the metadata store.
The openlineage-airflow plugin receives its configuration from environment variables. To populate these variables on Amazon MWAA, a custom Airflow plugin is used. First, the plugin reads source values from AWS Secrets Manager. Then, it creates environment variables.
Secrets Manager is configured as a secrets backend. Typically, this type of configuration is stored in Airflow’s native metadata database. However, this approach has limitations. For instance, in case of multiple Airflow environments, you need to track and store credentials across multiple environments, and updating credentials requires you to update all the environments. With a secrets backend, you can centralize configuration.
For demo purposes, we collect data lineage from a data pipeline, which creates a star schema in Redshift Serverless.
In the following sections, we walk you through the steps for end-to-end configuration.
Install the openlineage-airflow plugin
Specify the following dependency in the requirements.txt file of the Amazon MWAA environment. Note that the latest Airflow version currently available on Amazon MWAA is 2.4.3; for this post, use the compatible version 0.19.2 of the plugin:
For Airflow < 2.3, configure the plugin’s lineage backend through the following configuration overrides on the Amazon MWAA environment and load it immediately at Airflow start by disabling lazy load of plugins:
Configure the Secrets Manager backend with Amazon MWAA
Using Secrets Manager as a secrets backend for Amazon MWAA is straightforward. First, provide the execution role of Amazon MWAA with read permission to Secrets Manager. You can use the following policy template as a starting point:
Apache Airflow has a built-in plugin manager through which it can be extended with custom functionality. In our case, this functionality is to populate OpenLineage-specific environment variables based on values in Secrets Manager. Natively, Amazon MWAA allows environment variables with the prefix AIRFLOW__, but the openlineage-airflow plugin expects the prefix OPENLINEAGE__.
The following Python code is used in the plugin. We assume the file is called envvar_plugin.py:
from airflow.plugins_manager import AirflowPlugin
from airflow.models import Variable
import os

os.environ["OPENLINEAGE_URL"] = Variable.get('OPENLINEAGE_URL', default_var='')

class EnvVarPlugin(AirflowPlugin):
  name = "env_var_plugin"
Amazon MWAA has a mechanism to install a plugin through a zip archive. You zip your code, upload the archive to an S3 bucket, and pass the URL to the file to Amazon MWAA:
zip plugins.zip envvar_plugin.py
Upload plugins.zip to an S3 bucket and configure the URL in Amazon MWAA. The following screenshot shows the configuration via the Amazon MWAA console.
Configure connectivity between the openlineage-airflow plugin and Marquez
As a last step, store the URL to Marquez in Secrets Manager. For this, create a secret called airflow/variables/OPENLINEAGE_URL with value <protocol>://<hostname/ip>:<port> (for example, https://marquez.mysite.com:5000).
Update the value for the variable EXTERNAL_IP in constants.py to your outbound IP for connecting to the internet:
# Set variable to outbound IP for connecting to the internet.
EXTERNAL_IP = "255.255.255.255"
This configures security groups so that you can access Marquez but block other clients. constants.py is found in the root folder of the cloned repository.
Deploy the VPC_S3 stack to provision a new VPC dedicated for this solution as well as the security groups that are used by the different components:
cdk deploy vpc-s3
It creates a new S3 bucket and uploads the source raw data based on the TICKIT sample database. This serves as the landing area from the OLTP database. We then need to parse the metadata of these files through an AWS Glue crawler, which facilitates the native integration between Amazon Redshift and the S3 data lake.
Deploy the lineage stack to create an EC2 instance that hosts Marquez:
cdk deploy marquez
Access the Marquez web UI through https://{ec2.public_dns_name}:3000/. This URL is also available as part of the AWS CDK outputs for the lineage stack.
Deploy the Amazon Redshift stack to create a Redshift Serverless endpoint:
cdk deploy redshift
Deploy the Amazon MWAA stack to create an Amazon MWAA environment:
cdk deploy mwaa
You can access the Amazon MWAA UI through the URL provided in the AWS CDK output.
Test a sample data pipeline
On Amazon MWAA, you can see an example data pipeline deployed that consists of two DAGs. It builds a star schema on top of the TICKIT sample database. One DAG is responsible for loading data from the S3 data lake into an Amazon Redshift staging layer; the second DAG loads data from the staging layer to the dimensional model.
Open the Amazon MWAA UI through the URL obtained in the deployment steps and launch the following DAGs: rs_source_to_staging and rs_staging_to_dm. As part of the run, the lineage metadata is sent to Marquez.
After the DAG has been run, open the Marquez URL obtained in the deployment steps. In Marquez, you can find the lineage metadata for the computed star schema and related data assets on Amazon Redshift.
Clean up
Delete the AWS CDK stacks to avoid ongoing charges for the resources that you created. Run the following command in the aws-mwaa-openlineage project directory so that all resources are undeployed:
cdk destroy --all
Summary
In this post, we showed you how to automate data lineage with OpenLineage on Amazon MWAA. As part of this, we covered how to install and configure the openlineage-airflow plugin on Amazon MWAA. Additionally, we provided a ready-to-use infrastructure template for a complete demo environment.
We encourage you to explore what else can be achieved with OpenLineage. A job orchestrator like Apache Airflow is only one piece of a data platform and not all possible data lineage can be captured on it. We recommend exploring OpenLineage’s integration with other platforms like Apache Spark or dbt. For more information, refer to Integrations.
Additionally, we recommend you visit the AWS Big Data Blog for other useful blog posts on Amazon MWAA and data governance on AWS.
About the Authors
Stephen Said is a Senior Solutions Architect and works with Digital Native Businesses. His areas of interest are data analytics, data platforms and cloud-native software engineering.
Vishwanatha Nayak is a Senior Solutions Architect at AWS. He works with large enterprise customers helping them design and build secure, cost-effective, and reliable modern data platforms using the AWS cloud. He is passionate about technology and likes sharing knowledge through blog posts and twitch sessions.
Paul Villena is an Analytics Solutions Architect with expertise in building modern data and analytics solutions to drive business value. He works with customers to help them harness the power of the cloud. His areas of interests are infrastructure-as-code, serverless technologies and coding in Python.
In this post I will show you how to add a manual approval to AWS Cloud Development Kit (CDK) Pipelines to confirm security changes before deployment. With this solution, when a developer commits a change, CDK pipeline identifies an IAM permissions change, pauses execution, and sends a notification to a security engineer to manually approve or reject the change before it is deployed.
Introduction
In my role I talk to a lot of customers that are excited about the AWS Cloud Development Kit (CDK). One of the things they like is that L2 constructs often generate IAM and other security policies. This can save a lot of time and effort over hand coding those policies. Most customers also tell me that the policies generated by CDK are more secure than the policies they generate by hand.
However, these same customers are concerned that their security engineering team does not know what is in the policies CDK generates. In the past, these customers spent a lot of time crafting a handful of IAM policies that developers can use in their apps. These policies were well understood, but overly permissive because they were often reused across many applications.
Customers want more visibility into the policies CDK generates. Luckily CDK provides a mechanism to approve security changes. If you are using CDK, you have probably been prompted to approve security changes when you run cdk deploy at the command line. That works great on a developer’s machine, but customers want to build the same confirmation into their continuous delivery pipeline. CDK provides a mechanism for this with the ConfirmPermissionsBroadening action. Note that ConfirmPermissionsBroadening is only supported by the AWS CodePipline deployment engine.
Background
Before I talk about ConfirmPermissionsBroadening, let me review how CDK creates IAM policies. Consider the “Hello, CDK” application created in AWS CDK Workshop. At the end of this module, I have an AWS Lambda function and an Amazon API Gateway defined by the following CDK code.
// defines an AWS Lambda resource
const hello = new lambda.Function(this, 'HelloHandler', {
  runtime: lambda.Runtime.NODEJS_14_X,    // execution environment
  code: lambda.Code.fromAsset('lambda'),  // code loaded from "lambda" directory
  handler: 'hello.handler'                // file is "hello", function is "handler"
});

// defines an API Gateway REST API resource backed by our "hello" function.
new apigw.LambdaRestApi(this, 'Endpoint', {
  handler: hello
});
Note that I did not need to define the IAM Role or Lambda Permissions. I simply passed a refence to the Lambda function to the API Gateway (line 10 above). CDK understood what I was doing and generated the permissions for me. For example, CDK generated the following Lambda Permission, among others.
Notice that CDK generated a narrowly scoped policy, that allows a specific API (line 10 above) to call a specific Lambda function (line 7 above). This policy cannot be reused elsewhere. Later in the same workshop, I created a Hit Counter Construct using a Lambda function and an Amazon DynamoDB table. Again, I associated them using a single line of CDK code.
table.grantReadWriteData(this.handler);
As in the prior example, CDK generated a narrowly scoped IAM policy. This policy allows the Lambda function to perform certain actions (lines 4-11) on a specific table (line 14 below).
As you can see, CDK is doing a lot of work for me. In addition, CDK is creating narrowly scoped policies for each resource, rather than sharing a broadly scoped policy in multiple places.
CDK Pipelines Permissions Checks
Now that I have reviewed how CDK generates policies, let’s discuss how I can use this in a Continuous Deployment pipeline. Specifically, I want to allow CDK to generate policies, but I want a security engineer to review any changes using a manual approval step in the pipeline. Of course, I don’t want security to be a bottleneck, so I will only require approval when security statements or traffic rules are added. The pipeline should skip the manual approval if there are no new security rules added.
Let’s continue to use CDK Workshop as an example. In the CDK Pipelines module, I used CDK to configure AWS CodePipeline to deploy the “Hello, CDK” application I discussed above. One of the last things I do in the workshop is add a validation test using a post-deployment step. Adding a permission check is similar, but I will use a pre-deployment step to ensure the permission check happens before deployment.
First, I will import ConfirmPermissionsBroadening from the pipelines package
import {ConfirmPermissionsBroadening} from "aws-cdk-lib/pipelines";
Then, I can simply add ConfirmPermissionsBroadening to the deploySatage using the addPre method as follows.
const deploy = new WorkshopPipelineStage(this, 'Deploy');
const deployStage = pipeline.addStage(deploy);

deployStage.addPre(
  new ConfirmPermissionsBroadening("PermissionCheck", {
    stage: deploy
})

deployStage.addPost(
    // Post Deployment Test Code Omitted
)
Once I commit and push this change, a new manual approval step called PermissionCheck.Confirm is added to the Deploy stage of the pipeline. In the future, if I push a change that adds additional rules, the pipeline will pause here and await manual approval as shown in the screenshot below.
Figure 1. Pipeline waiting for manual review
When the security engineer clicks the review button, she is presented with the following dialog. From here, she can click the URL to see a summary of the change I am requesting which was captured in the build logs. She can also choose to approve or reject the change and add comments if needed.
Figure 2. Manual review dialog with a link to the build logs
When the security engineer clicks the review URL, she is presented with the following sumamry of security changes.
Figure 3. Summary of security changes in the build logs
The final feature I want to add is an email notification so the security engineer knows when there is something to approve. To accomplish this, I create a new Amazon Simple Notification Service (SNS) topic and subscription and associate it with the ConfirmPermissionsBroadening Check.
// Create an SNS topic and subscription for security approvals
const topic = new sns.Topic(this, 'SecurityApproval’);
topic.addSubscription(new subscriptions.EmailSubscription('[email protected]'));

deployStage.addPre(
  new ConfirmPermissionsBroadening("PermissionCheck", {
    stage: deploy,
    notificationTopic: topic
})
With the notification configured, the security engineer will receive an email when an approval is needed. She will have an opportunity to review the security change I made and assess the impact. This gives the security engineering team the visibility they want into the policies CDK is generating. In addition, the approval step is skipped if a change does not add security rules so the security engineer does not become a bottle neck in the deployment process.
Conclusion
AWS Cloud Development Kit (CDK) automates the generation of IAM and other security policies. This can save a lot of time and effort but security engineering teams want visibility into the policies CDK generates. To address this, CDK Pipelines provides the ConfirmPermissionsBroadening action. When you add ConfirmPermissionsBroadening to your CI/CD pipeline, CDK will wait for manual approval before deploying a change that includes new security rules.
With AWS Lake Formation, you can build data lakes with multiple AWS accounts in a variety of ways. For example, you could build a data mesh, implementing a centralized data governance model and decoupling data producers from the central governance. Such data lakes enable the data as an asset paradigm and unleash new possibilities with data discovery and exploration across organization-wide consumers. While enabling the power of data in decision-making across your organization, it’s also crucial to secure the data. With Lake Formation, sharing datasets across accounts only requires a few simple steps, and you can control what you share.
Lake Formation has launched Version 3 capabilities for sharingAWS Glue Data Catalog resources across accounts. When moving to Lake Formation cross-account sharing V3, you get several benefits. When moving from V1, you get more optimized usage of AWS Resource Access Manager (AWS RAM) to scale sharing of resources. When moving from V2, you get a few enhancements. First, you don’t have to maintain AWS Glue resource policies to share using LF-tags because Version 3 uses AWS RAM. Second, you can share with AWS Organizations using LF-tags. Third, you can share to individual AWS Identity and Access Management (IAM) users and roles in other accounts, thereby providing data owners control over which individuals can access their data.
Lake Formation tag-based access control (LF-TBAC) is an authorization strategy that defines permissions based on attributes called LF-tags. LF-tags are different from IAM resource tags and are associated only with Lake Formation databases, tables, and columns. LF-TBAC allows you to define the grant and revoke permissions policy by grouping Data Catalog resources, and therefore helps in scaling permissions across a large number of databases and tables. LF-tags are inherited from a database to all its tables and all the columns of each table.
Version 3 offers the following benefits:
True central governance with cross-account sharing to specific IAM principals in the target account
Ease of use in not having to maintain an AWS Glue resource policy for LF-TBAC
Efficient reuse of AWS RAM shares
Ease of use in scaling to hundreds of accounts with LF-TBAC
In this post, we illustrate the new features of cross-account sharing Version 3 in a producer-consumer scenario using TPC datasets. We walk through the setup of using LF-TBAC to share data catalog resources from the data producer account to direct IAM users in the consumer account. We also go through the steps in the receiving account to accept the shares and query the data.
As a data producer, register the dataset with Lake Formation and create AWS Glue Data Catalog tables.
Create LF-tags and associate them with the database and tables.
Grant LF-tag based permissions on resources directly to personas in consumer account B.
The following steps take place in account B:
The consumer account data lake admin reviews and accepts the AWS RAM invitations.
The data lake admin gives CREATE DATABASE access to the IAM user lf_business_analysts.
The data lake admin creates a database for the marketing team and grants CREATE TABLE access to lf_campaign_manager.
The IAM users create resource links on the shared database and tables and query them in Amazon Athena.
The producer account A has the following personas:
Data lake admin – Manages the data lake in the producer account
lf-producersteward – Manages the data and user access
The consumer account B has the following personas:
Data lake admin – Manages the data lake in the consumer account
lf-business-analysts – The business analysts in the sales team needs access to non-PII data
lf-campaign-manager – The manager in the marketing team needs access to data related to products and promotions
Prerequisites
You need the following prerequisites:
Two AWS accounts. For this demonstration of how AWS RAM invites are created and accepted, you should use two accounts that are not part of the same organization.
An admin IAM user in both accounts to launch the AWS CloudFormation stacks.
Lake Formation mode enabled in both the producer and consumer account with cross-account Version 3. For instructions, refer to Change the default permission model.
Lake Formation and AWS CloudFormation setup in account A
To keep the setup simple, we have an IAM admin registered as the data lake admin.
If CloudShell isn’t available in your chosen Region, run the following AWS CLI command to copy the required dataset from your preferred AWS CLI environment as the IAM admin user.
Verify that your S3 bucket has the dataset copied in it.
Log out as the IAM admin user.
Grant permissions in account A
Next, we continue granting Lake Formation permissions to the dataset as a data steward within the producer account. The data steward grants the following LF-tag-based permissions to the consumer personas.
Consumer Persona
LF-tag Policy
lf-business-analysts
Sensitivity=Public
lf-campaign-manager
HasCampaign=true
Log in to account A as user lf-producersteward, using the password you noted from Secrets Manager earlier.
On the Lake Formation console, under Permissions in the navigation pane, choose Data Lake permissions.
Choose Grant.
Under Principals, select External accounts.
Provide the ARN of the IAM user in the consumer account (arn:aws:iam::<accountB_id>:user/lf-business-analysts) and press Enter.
Under LF_Tags or catalog resources, select Resources matched by LF-Tags.
Choose Add LF-Tag to add a new key-value pair.
For the key, choose Sensitivity and for the value, choose Public.
Under Database permissions, select Describe, and under Table permissions, select Select and Describe.
Choose Grant to apply the permissions.
On the Lake Formation console, under Permissions in the navigation pane, choose Data Lake permissions.
Choose Grant.
Under Principals, select External accounts.
Provide the ARN of the IAM user in the consumer account (arn:aws:iam::<accountB_id>:user/lf-campaign-manager) and press Enter.
Under LF_Tags or catalog resources, select Resources matched by LF-Tags.
Choose Add LF-Tag to add a new key-value pair.
For the key, choose HasCampaign and for the value, choose true.
Under Database permissions, select Describe, and under Table permissions, select Select and Describe.
Choose Grant to apply the permissions.
Verify on the Data lake permissions tab that the permissions you have granted show up correctly.
AWS CloudFormation setup in account B
Complete the following steps in the consumer account:
Log in as an IAM admin user in account B and launch the CloudFormation stack:
Choose Next.
Provide a name for the stack, then choose Next.
On the next page, choose Next.
Review the details on the final page and select I acknowledge that AWS CloudFormation might create IAM resources.
Choose Create.
Stack creation should take about 2–3 minutes. The stack sets up the following resources in account B:
IAM users datalakeadmin1, lf-business-analysts, and lf-campaign-manager, with relevant IAM and Lake Formation permissions
A database called db_for_shared_tables with Create_Table permissions to the lf-campaign-manager user
An S3 bucket named lfblog-athenaresults-<your-accountB-id>-us-east-1 with ListBucket and write permissions to lf-business-analysts and lf-campaign-manager
Note down the stack output details.
Accept resource shares in account B
After you launch the CloudFormation stack, complete the following steps in account B:
On the CloudFormation stack Outputs tab, choose the link for DataLakeAdminCredentials.
This takes you to the Secrets Manager console.
On the Secrets Manager console, choose Retrieve secret value and copy the password for DataLakeAdmin user.
Use the ConsoleIAMLoginURL value from the CloudFormation template output to log in to account B with the data lake admin user name datalakeadmin1 and the password you copied from Secrets Manager.
Open the AWS RAM console in another browser tab.
In the navigation pane, under Shared with me, choose Resource shares to view the pending invitations.
You should see two resource share invitations from the producer account A: one for database-level share and one for table-level share.
Choose each resource share link, review the details, and choose Accept.
After you accept the invitations, the status of the resource shares changes from Active from Pending.
Grant permissions in account B
To grant permissions in account B, complete the following steps:
On the Lake Formation console, under Permissions on the navigation pane, choose Administrative roles and tasks.
Under Database creators, choose Grant.
Under IAM users and roles, choose lf-business-analysts.
For Catalog permissions, select Create database.
Choose Grant.
Log out of the console as the data lake admin user.
Query the shared datasets as consumer users
To validate the lf-business-analysts user’s data access, perform the following steps:
Log in to the console as lf-business-analysts, using the credentials noted from the CloudFormation stack output.
On the Lake Formation console, under Data catalog in the navigation pane, choose Databases.
Select the database lftpcdb and on the Actions menu, choose Create resource link.
Under Resource link name, enter rl_lftpcdb.
Choose Create.
After the resource link is created, select the resource link and choose View tables.
You can now see the four tables in the shared database.
Open the Athena console in another browser tab and choose the lfblog-athenaresults-<your-accountB-id>-us-east-1 bucket as the query results location.
Notice that account A shared the database lftpcdb to account B using the LF-tag expression Sensitivity=Public. Columns c_first_name, c_last_name, and c_email_address in table customers were overwritten with Sensitivity=Confidential. Therefore, these three columns are not visible to user lf-business-analysts.
You can preview the other tables from the database similarly to see the available columns and data.
Log out of the console as lf-business-analysts.
Now we can validate the lf-campaign-manager user’s data access.
Log in to the console as lf-campaign-manager using the credentials noted from the CloudFormation stack output.
On the Lake Formation console, under Data catalog in the navigation pane, choose Databases.
Verify that you can see the database db_for_shared_tables shared by the data lake admin.
Under Data catalog in the navigation pane, choose Tables.
You should be able to see the two tables shared from account A using the LF-tag expression HasCampaign=true. The two tables show the Owner account ID as account A.
Because lf-campaign-manager received table level shares, this user will create table-level resource links for querying in Athena.
Select the promotions table, and on the Actions menu, choose Create resource link.
For Resource link name, enter rl_promotions.
Under Database, choose db_for_shared_tables for the database to contain the resource link.
Choose Create.
Repeat the table resource link creation for the other table items.
Notice that the resource links show account B as owner, whereas the actual tables show account A as the owner.
Open the Athena console in another browser tab and choose the lfblog-athenaresults-<your-accountB-id>-us-east-1 bucket as the query results location.
11. Query the tables using the resource links.
As shown in the following screenshot, all columns of both tables are accessible to lf-campaign-manager.
In summary, you have seen how LF-tags are used to share a database and select tables from one account to another account’s IAM users.
Clean up
To avoid incurring charges on the AWS resources created in this post, you can perform the following steps.
First, clean up resources in account A:
Empty the S3 bucket created for this post by deleting the downloaded objects from your S3 bucket.
Delete the CloudFormation stack.
This deletes the S3 bucket, custom IAM roles, policies, and the LF database, tables, and permissions.
You may choose to undo the Lake Formation settings also and add IAM access back from the Lake Formation console Settings page.
Now complete the following steps in account B:
Empty the S3 bucket lfblog-athenaresults-<your-accountB-id>-us-east-1 used as the Athena query results location.
Revoke permission to lf-business-analysts as database creator.
Delete the CloudFormation stack.
This deletes the IAM users, S3 bucket, Lake Formation database db_for_shared_tables, resource links, and all the permissions from Lake Formation.
If there are any resource links and permissions left, delete them manually in Lake Formation from both accounts.
Conclusion
In this post, we illustrated the benefits of using Lake Formation cross-account sharing Version 3 using LF-tags to direct IAM principals and how to receive the shared tables in the consumer account. We used a two-account scenario in which a data producer account shares a database and specific tables to individual IAM users in another account using LF-tags. In the receiving account, we showed the role played by a data lake admin vs. the receiving IAM users. We also illustrated how to overwrite column tags to mask and share PII data.
With Version 3 of cross-account sharing features, Lake Formation makes possible more modern data mesh models, where a producer can directly share to an IAM principal in another account, instead of the entire account. Data mesh implementation becomes easier for data administrators and data platform owners because they can easily scale to hundreds of consumer accounts using the LF-tags based sharing to organizational units or IDs.
Aarthi Srinivasan is a Senior Big Data Architect with AWS Lake Formation. She likes building data lake solutions for AWS customers and partners. When not on the keyboard, she explores the latest science and technology trends and spends time with her family.
Srividya Parthasarathy is a Senior Big Data Architect on the AWS Lake Formation team. She enjoys building analytics and data mesh solutions on AWS and sharing them with the community.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.


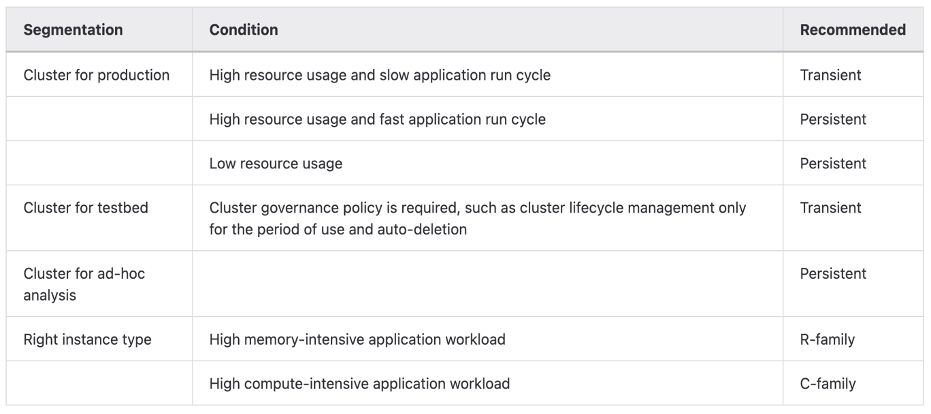
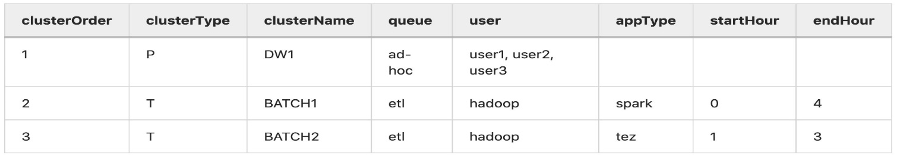
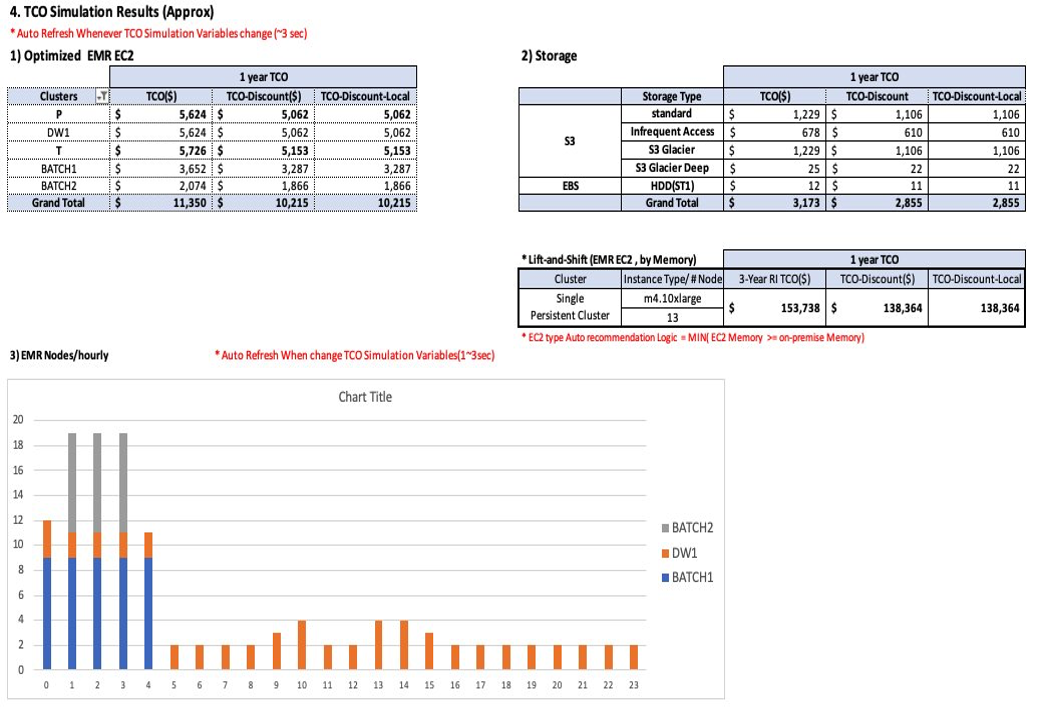
 Sungyoul Park is a Senior Practice Manager at AWS ProServe. He helps customers innovate their business with AWS Analytics, IoT, and AI/ML services. He has a specialty in big data services and technologies and an interest in building customer business outcomes together.
 Jiseong Kim is a Senior Data Architect at AWS ProServe. He mainly works with enterprise customers to help data lake migration and modernization, and provides guidance and technical assistance on big data projects such as Hadoop, Spark, data warehousing, real-time data processing, and large-scale machine learning. He also understands how to apply technologies to solve big data problems and build a well-designed data architecture.
 George Zhao is a Senior Data Architect at AWS ProServe. He is an experienced analytics leader working with AWS customers to deliver modern data solutions. He is also a ProServe Amazon EMR domain specialist who enables ProServe consultants on best practices and delivery kits for Hadoop to Amazon EMR migrations. His area of interests are data lakes and cloud modern data architecture delivery.
 Kalen Zhang was the Global Segment Tech Lead of Partner Data and Analytics at AWS. As a trusted advisor of data and analytics, she curated strategic initiatives for data transformation, led data and analytics workload migration and modernization programs, and accelerated customer migration journeys with partners at scale. She specializes in distributed systems, enterprise data management, advanced analytics, and large-scale strategic initiatives.

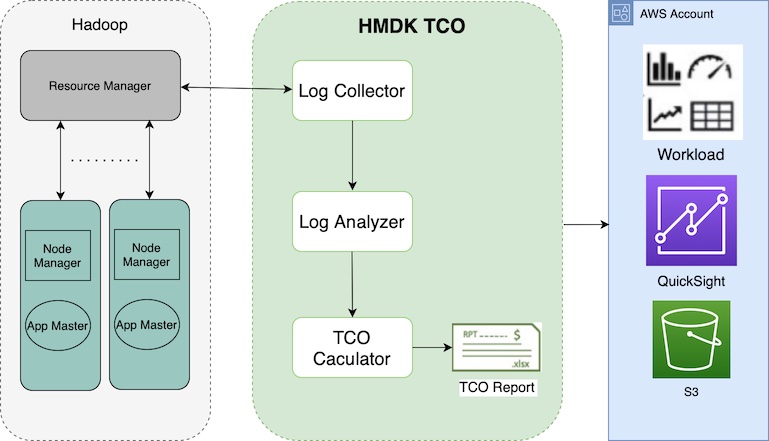
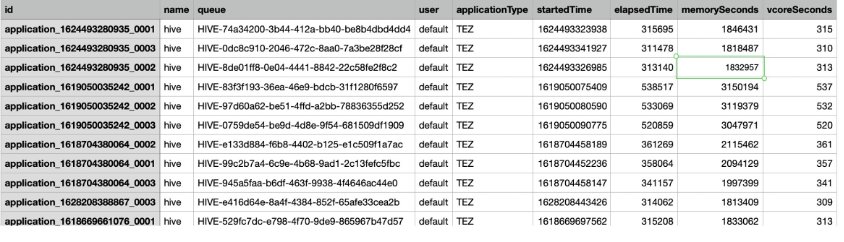
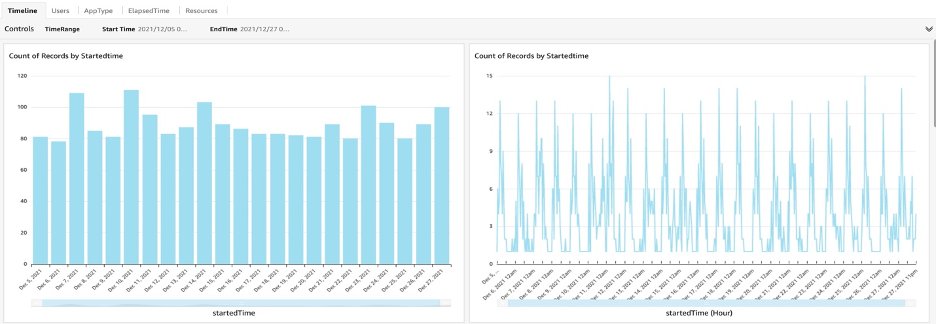

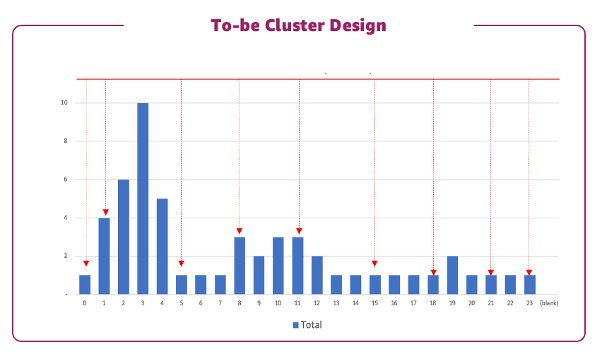


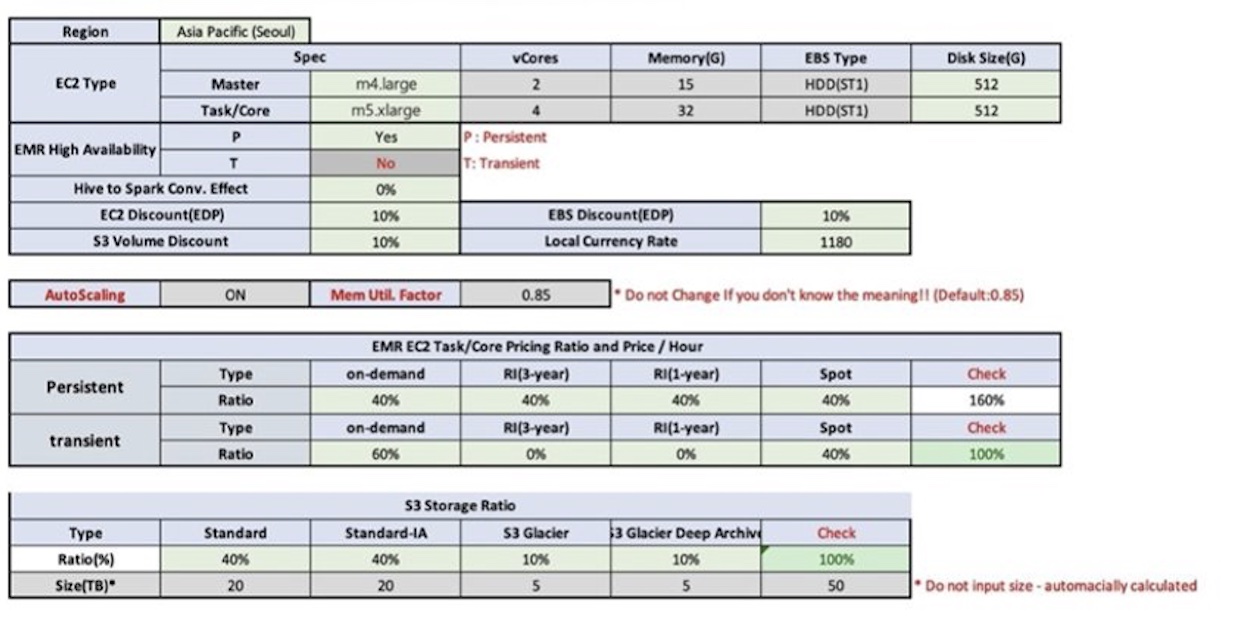


 Payal Singh is a Partner Solutions Architect at Amazon Web Services, focused on the Serverless platform. She is responsible for helping partner and customers modernize and migrate their applications to AWS.


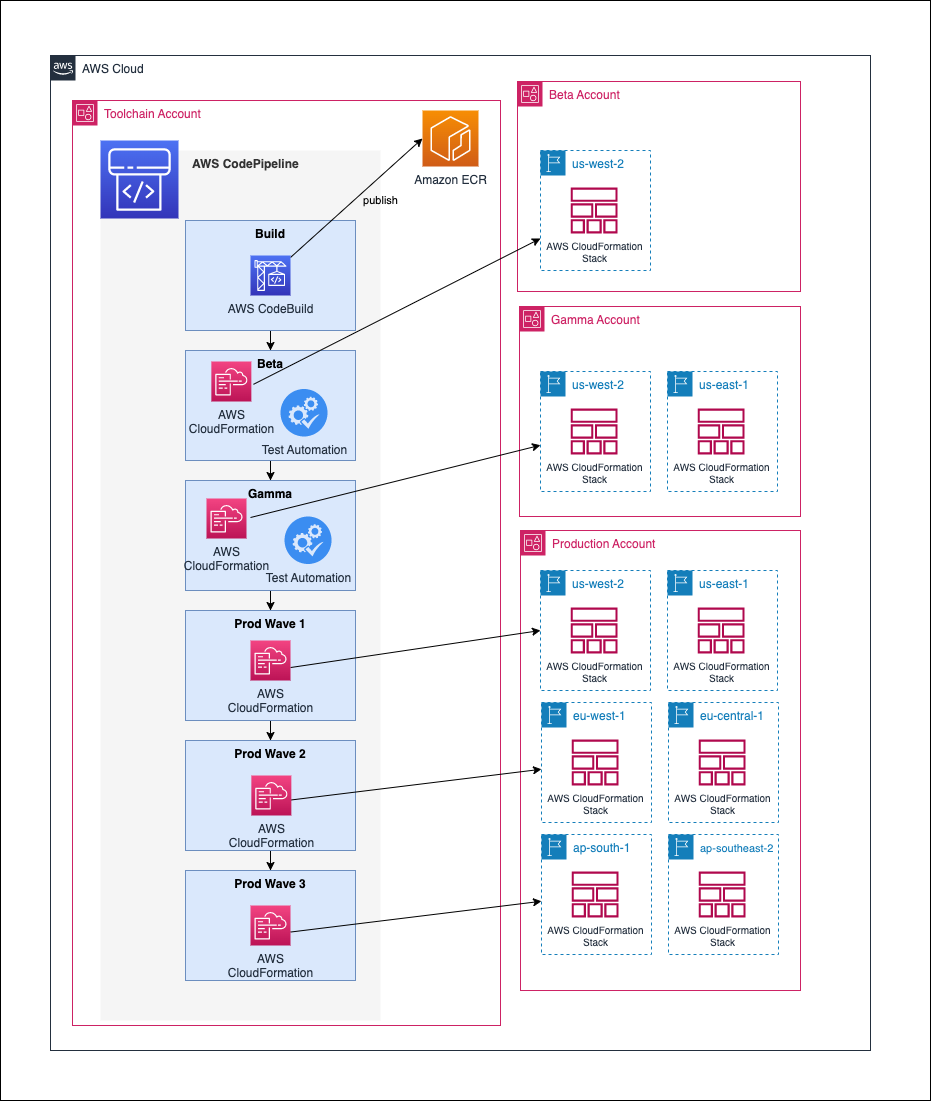


 Sekar Srinivasan is a Sr. Specialist Solutions Architect at AWS focused on Big Data and Analytics. Sekar has over 20 years of experience working with data. He is passionate about helping customers build scalable solutions modernizing their architecture and generating insights from their data. In his spare time he likes to work on non-profit projects, especially those focused on underprivileged Children’s education.
 Prabu Ravichandran is a Senior Data Architect with Amazon Web Services, focussed on Analytics, data Lake architecture and implementation. He helps customers architect and build scalable and robust solutions using AWS services. In his free time, Prabu enjoys traveling and spending time with family.
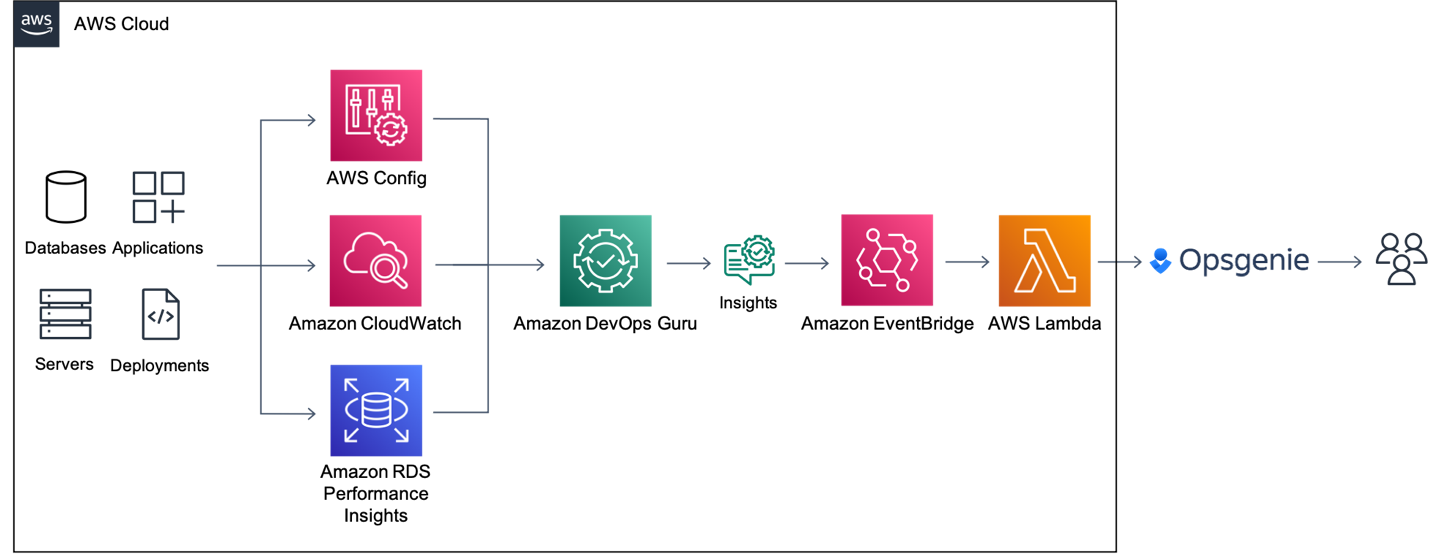




 David Zhang is an AWS Data Architect in Global Financial Services. He specializes in designing and implementing serverless analytics infrastructure, data management, ETL, and big data systems. He helps customers modernize their data platforms on AWS. David is also an active speaker and contributor to AWS conferences, technical content, and open-source initiatives. During his free time, he enjoys playing volleyball, tennis, and weightlifting. Feel free to connect with him on
 Manash Deb is a Software Development Manager in the AWS Directory Service team. With over 18 years of software dev experience, his passion is designing and delivering highly scalable, secure, zero-maintenance applications in the AWS identity and data analytics space. He loves mentoring and coaching others and to act as a catalyst and force multiplier, leading highly motivated engineering teams, and building large-scale distributed systems.
 Pavan Kumar Vadupu Lakshman Manikya is an AWS Solutions Architect who helps customers design robust, scalable solutions across multiple industries. With a background in enterprise architecture and software development, Pavan has contributed in creating solutions to handle API security, API management, microservices, and geospatial information system use cases for his customers. He is passionate about learning new technologies and solving, automating, and simplifying customer problems using these solutions.




 Stephen Said is a Senior Solutions Architect and works with Digital Native Businesses. His areas of interest are data analytics, data platforms and cloud-native software engineering.
 Vishwanatha Nayak is a Senior Solutions Architect at AWS. He works with large enterprise customers helping them design and build secure, cost-effective, and reliable modern data platforms using the AWS cloud. He is passionate about technology and likes sharing knowledge through blog posts and twitch sessions.
 Paul Villena is an Analytics Solutions Architect with expertise in building modern data and analytics solutions to drive business value. He works with customers to help them harness the power of the cloud. His areas of interests are infrastructure-as-code, serverless technologies and coding in Python.


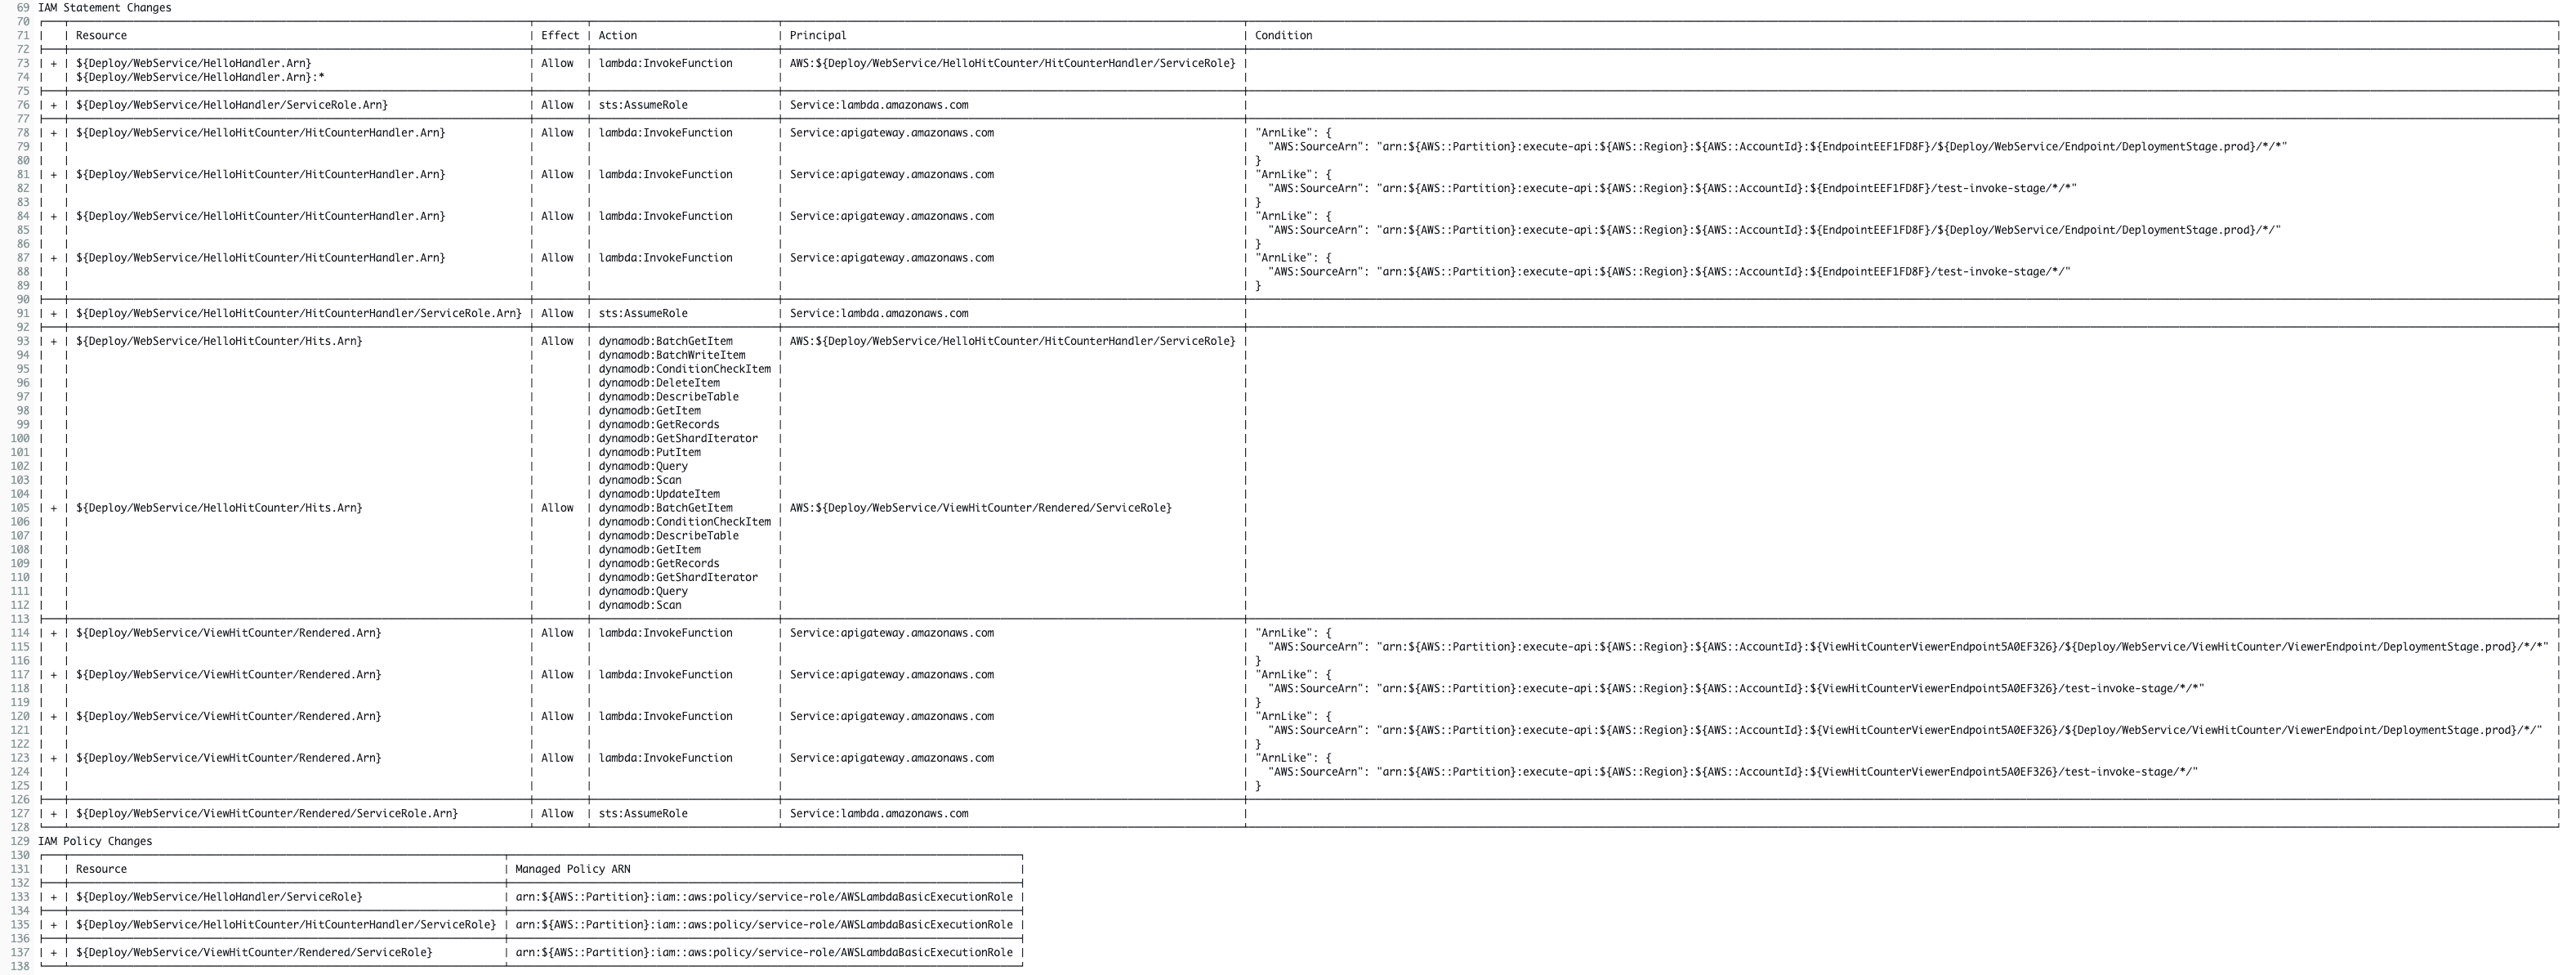


 Aarthi Srinivasan is a Senior Big Data Architect with AWS Lake Formation. She likes building data lake solutions for AWS customers and partners. When not on the keyboard, she explores the latest science and technology trends and spends time with her family.
 Srividya Parthasarathy is a Senior Big Data Architect on the AWS Lake Formation team. She enjoys building analytics and data mesh solutions on AWS and sharing them with the community.