Tag Archives: Compute

Accelerate large-scale AI applications with the new Amazon EC2 P6-B300 instances

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/accelerate-large-scale-ai-applications-with-the-new-amazon-ec2-p6-b300-instances/

Today, we’re announcing the general availability of Amazon Elastic Compute Cloud (Amazon EC2) P6-B300 instances, our next-generation GPU platform accelerated by NVIDIA Blackwell Ultra GPUs. These instances deliver 2 times more networking bandwidth, and 1.5 times more GPU memory compared to previous generation instances, creating a balanced platform for large-scale AI applications.

With these improvements, P6-B300 instances are ideal for training and serving large-scale AI models, particularly those employing sophisticated techniques such as Mixture of Experts (MoE) and multimodal processing. For organizations working with trillion-parameter models and requiring distributed training across thousands of GPUs, these instances provide the perfect balance of compute, memory, and networking capabilities.

Improvements made compared to predecessors
The P6-B300 instances deliver 6.4Tbps Elastic Fabric Adapter (EFA) networking bandwidth, supporting efficient communication across large GPU clusters. These instances feature 2.1TB of GPU memory, allowing large models to reside within a single NVLink domain, which significantly reduces model sharding and communication overhead. When combined with EFA networking and the advanced virtualization and security capabilities of AWS Nitro System, these instances provide unprecedented speed, scale, and security for AI workloads.

The specs for the EC2 P6-B300 instances are as follows.

Instance size VCPUs System memory GPUs GPU memory GPU-GPU interconnect EFA network bandwidth ENA bandwidth EBS bandwidth Local storage
P6-B300.48xlarge 192 4TB 8x B300 GPU 2144GB HBM3e 1800 GB/s 6.4 Tbps 300 Gbps 100 Gbps 8x 3.84TB

Good to know
In terms of persistent storage, AI workloads primarily use a combination of high performance persistent storage options such as Amazon FSx for Lustre, Amazon S3 Express One Zone, and Amazon Elastic Block Store (Amazon EBS), depending on price performance considerations. For illustration, the dedicated 300Gbps Elastic Network Adapter (ENA) networking on P6-B300 enables high-throughput hot storage access with S3 Express One Zone, supporting large-scale training workloads. If you’re using FSx for Lustre, you can now use EFA with GPUDirect Storage (GDS) to achieve up to 1.2Tbps of throughput to the Lustre file system on the P6-B300 instances to quickly load your models.

Available now
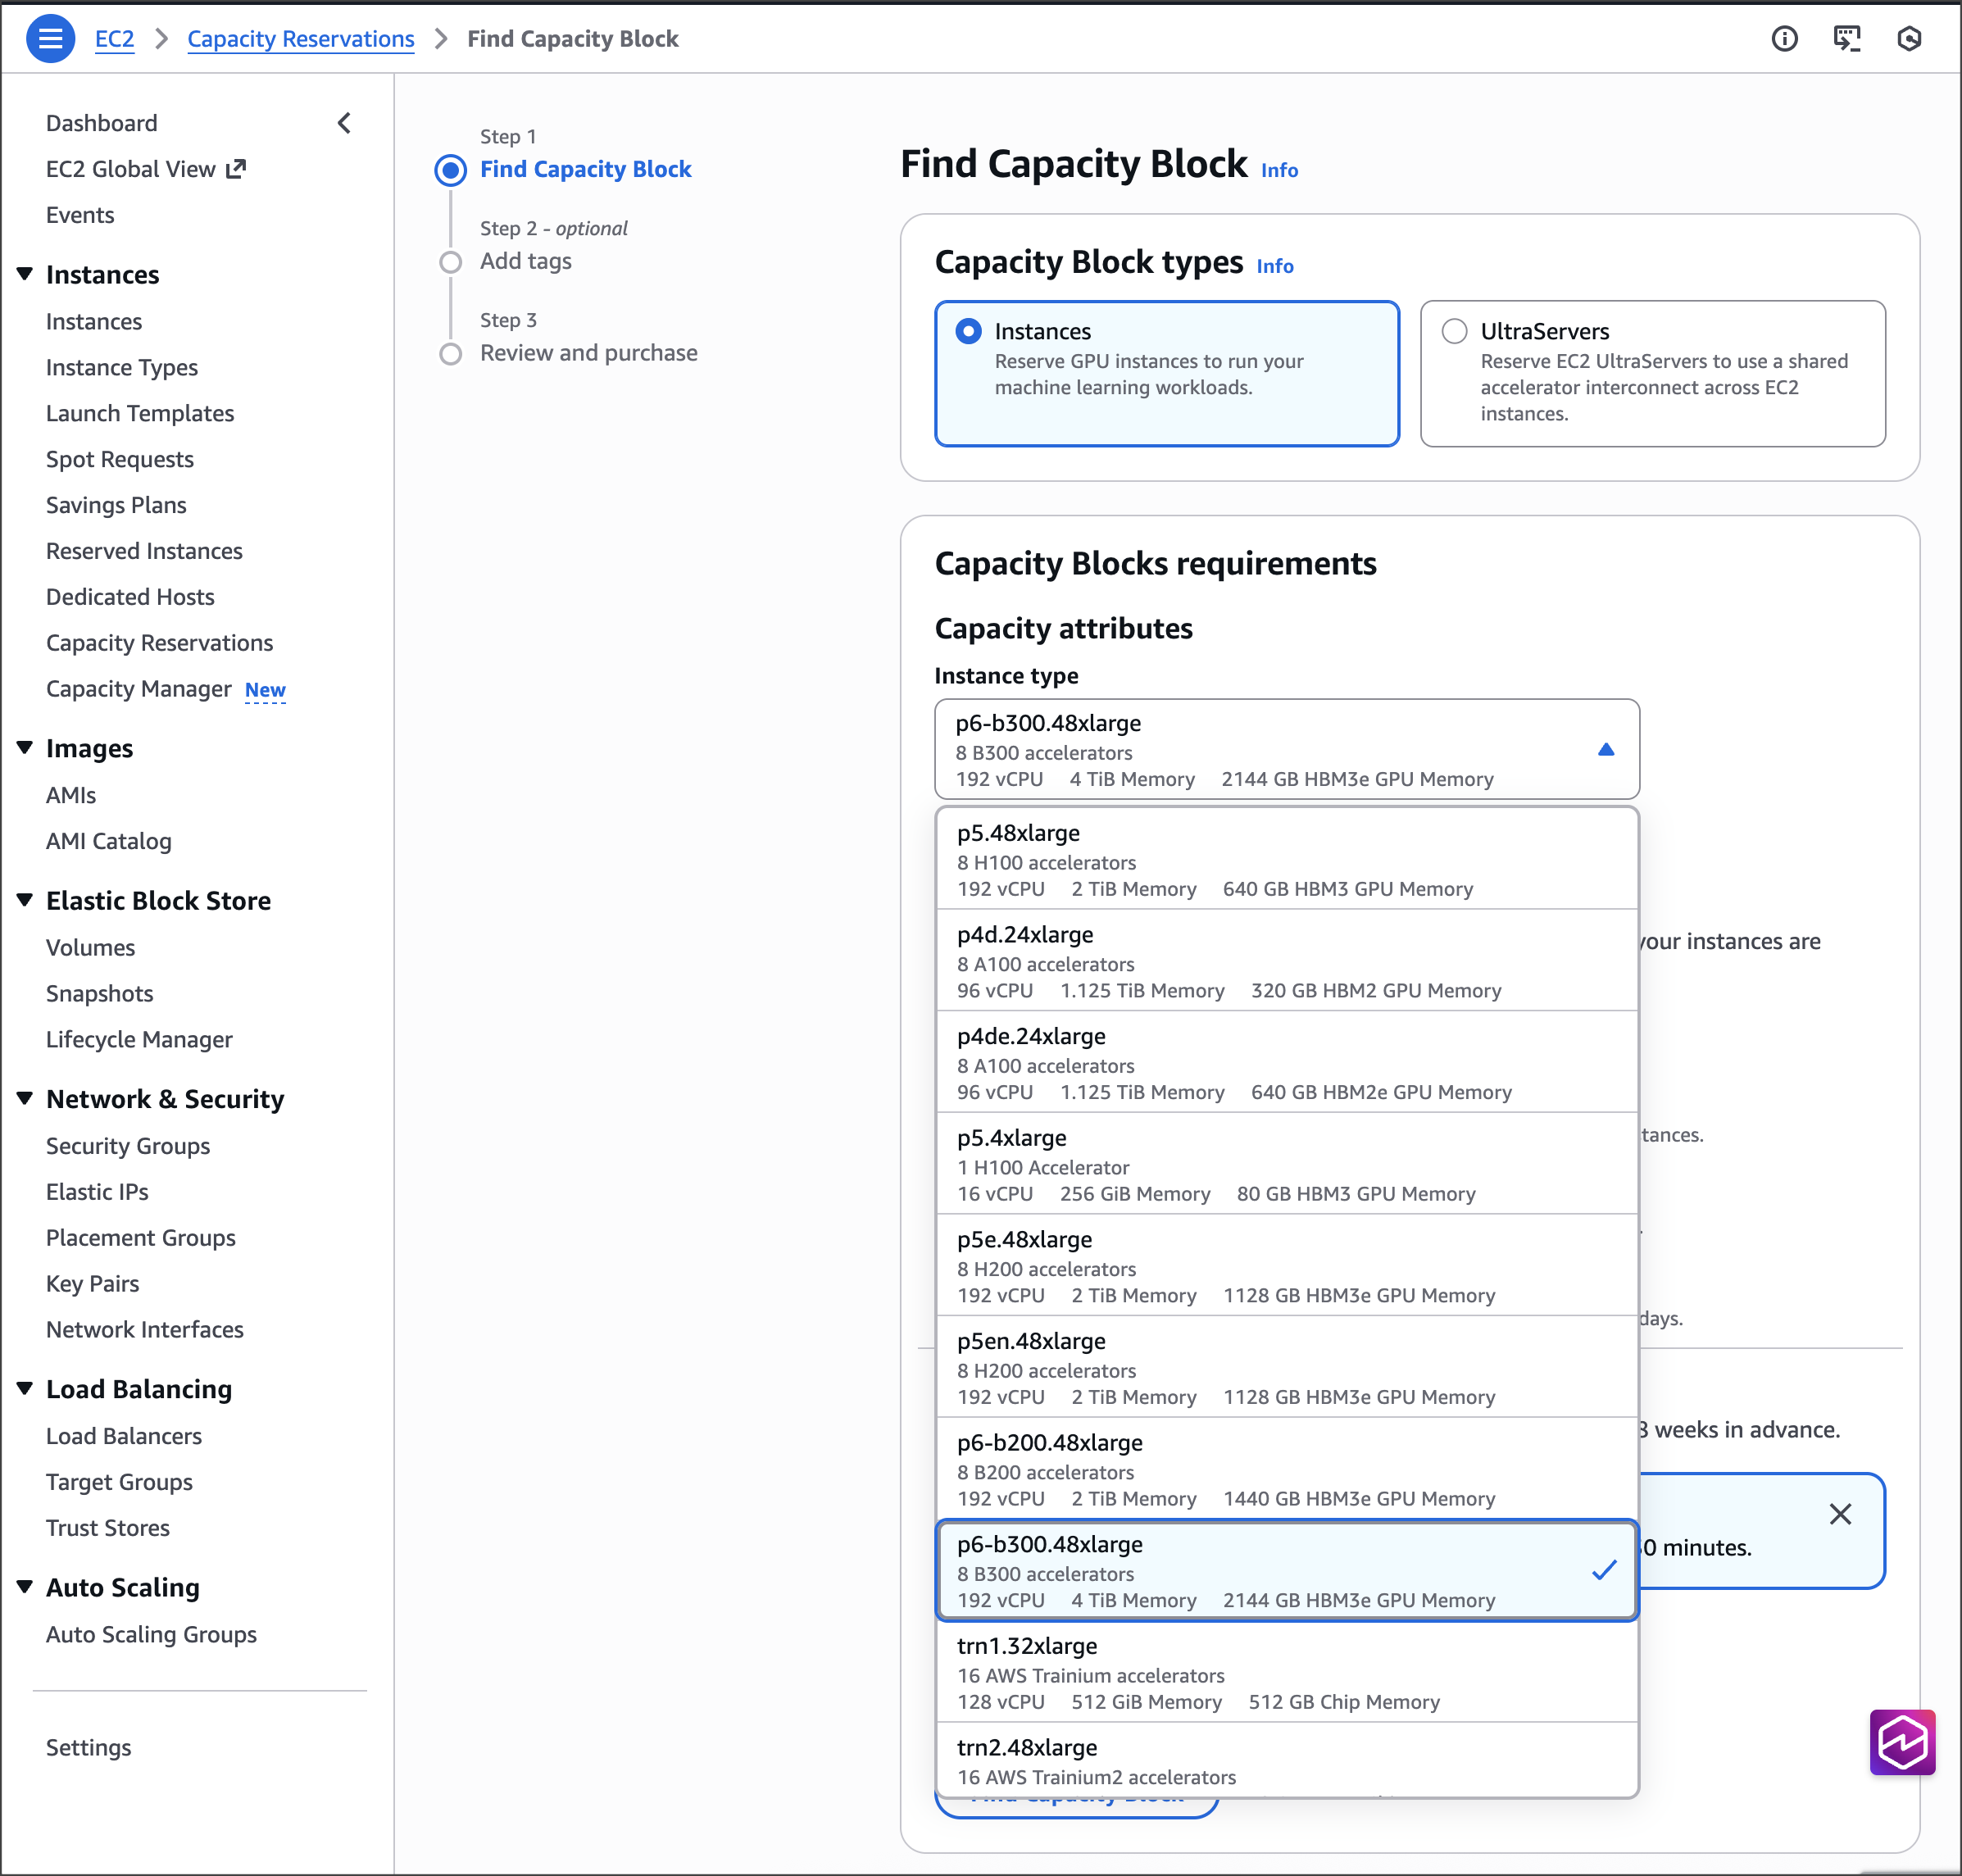
The P6-B300 instances are now available through Amazon EC2 Capacity Blocks for ML and Savings Planin the US West (Oregon) AWS Region.
For on-demand reservation of P6-B300 instances, please reach out to your account manager. As usual with Amazon EC2, you pay only for what you use. For more information, refer to Amazon EC2 Pricing. Check out the full collection of accelerated computing instances to help you start migrating your applications.

To learn more, visit our Amazon EC2 P6-B300 instances page. Send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

– Veliswa

The attendee’s guide to the AWS re:Invent 2025 Compute track

Post Syndicated from Mai Kulkarni original https://aws.amazon.com/blogs/compute/the-attendees-guide-to-the-aws-reinvent-2025-compute-track/

From December 1st to December 5th, Amazon Web Services (AWS) will hold its annual premier learning event: re:Invent. At this event, attendees can become stronger and more proficient in any area of AWS technology through a variety of experiences: large keynotes given by AWS leaders, smaller innovation talks, interactive working sessions given by AWS experts, and fun activities such as live music and games at re:Play.

There are over 2000+ learning sessions that focus on specific topics at various skill levels, and the compute team have created 76 unique sessions for you to choose. There are many sessions you can choose from, and we are here to help you choose the sessions that best fit your needs. Even if you cannot join in person, you can catch-up with many of the sessions on-demand and even watch the keynote and innovation sessions live.

The basics: Session types

If you can join us, then remember that we offer several types of sessions that can help maximize your learning in a variety of AWS topics.

re:Invent attendees can also choose to attend chalk-talks, builder sessions, workshops, or code talk sessions. Each of these are live non-recorded interactive sessions.

  • Breakout sessions: Attendees are in a lecture-style 60-minute informative sessions presented by AWS experts, customers, or partners. These sessions are recorded and uploaded a few days after to the AWS Events YouTube channel.
  • Chalk-talk sessions: Attendees interact with presenters, asking questions, and using a whiteboard in session.
  • Builder Sessions: Attendees participate in a one-hour session and build something.
  • Workshops sessions: Attendees join a two-hour interactive session where they work in a small team to solve a real problem using AWS services.
  • Code talk sessions: Attendees participate in engaging code-focused sessions where an expert leads a live coding session.
  • Lightning talk sessions: Attendees watch a 20-minute demo dedicated to either a specific service or customer story (located in the Venetian Expo Hall or Mandalay Bay Level 2 South).

Getting started with Amazon EC2

The foundation of compute in AWS is Amazon Elastic Compute Cloud (Amazon EC2). Amazon EC2 offers the broadest and deepest compute platform, with over 1000 instances and choice of the latest processor, storage, networking, operating system, and purchase model to help you best match the needs of your workload. We’ve created the following sessions to help you implement and manage your workloads on EC2.

CMP356 | How well do you know EC2

EC2 offers 1000+ instance types with diverse processors, accelerators, and the AWS Nitro System. Options include cost-effective Spot Instances and Savings Plans. Learn how to optimize workload-instance matching for better performance and savings.

CMP343 | Select and launch the right instance for your workload and budget

Explore the newest EC2 instances featuring Intel Xeon Scalable (Granite Rapids), AMD EPYC (Turin), and AWS Graviton processors. Learn how to choose the optimal instance type for your workload and budget requirements.

CMP305 | Assembling the Complete AI Stack: Optimizing your AI hardware on AWS

Learn how to optimize your AI infrastructure on AWS: Choose the right processors, accelerators, storage, and pricing models for your workloads. Get practical guidance on GPU selection, vector databases, and building cost-effective, scalable AI platforms.

CMP332 | Mastering EC2 Image Builder: From basics to advanced techniques

Hands-on session: Build an automated image pipeline with AWS experts. Learn the basics and advanced features such as multi-account distribution and continuous integration/continuous development (CI/CD) integration in 60 minutes.

CMP331 | Managing Amazon EC2 capacity and availability

Learn how to optimize EC2 costs and capacity using different reservation models, such as On-Demand, Capacity Blocks for machine learning (ML), and capacity reservations, to improve efficiency and availability.

CMP330 | Use Auto Scaling to proactively scale and optimize EC2 workloads

Learn how to harness the latest features of EC2 Auto Scaling to optimize your cloud resources. This hands-on workshop covers predictive scaling, dynamic scaling, and warm pools to automatically manage capacity based on demand. This is perfect for those wanting to improve application availability while reducing costs. Bring your laptop for practical exercises.

Learn about AWS Compute innovations

AWS has invested years into designing custom silicon optimized for the cloud to deliver the best price performance for a wide range of applications and workloads using AWS services. Learn more about the AWS Nitro System, processors at AWS, and ML chips.

CMP316 | Deep Dive into the AWS Nitro System

Explore the architecture behind the groundbreaking AWS Nitro System: the custom hardware and security components driving modern EC2 instances. Learn how this innovative platform enables unprecedented compute, storage, and networking capabilities, and discover the latest advances making new cloud possibilities reality.

CMP307 | AWS Graviton: The best price performance for your AWS workloads

Explore how AWS Graviton processors deliver superior performance and energy efficiency in EC2. Learn optimization best practices, common use cases, and customer success stories to accelerate your AWS Graviton adoption journey.

CMP336 | Optimize network and Amazon EBS intensive workloads on Amazon EC2 instances

Discover how to maximize the EC2 network and Amazon Elastic Block Store (Amazon EBS)-optimized instances for high-performance workloads. Learn to use new AWS Graviton and Intel instances for security appliances, databases, and network-intensive applications. Get practical insights into the latest networking and storage technologies to optimize your EC2 workload performance.

CMP315 | Maximizing EC2 Local NVMe Storage: Enhanced NVMe Metrics and Kubernetes Integration

Learn to optimize data-intensive workloads using AWS Nitro SSDs. Explore new performance metrics (latency, IOPS, throughput) and best practices for monitoring and tuning application performance.

CMP407 | Innovating with AWS confidential computing: An integrated approach

Learn how AWS confidential computing (Nitro System, Enclaves, TPM) protects sensitive data during processing. Explore solutions for secure data handling across CPU, GPU, and AI workloads.

CMP302 | Accelerating engineering: Cross-industry HPC cloud transformations

Discover how AWS high performance computing (HPC) transformed engineering and product development across industries. Learn how customers used cloud HPC to revolutionize their design processes to reduce time-to-market and increase innovation efficiency. Observe how HPC instances, Elastic Fabric Adapter (EFA), Amazon FSx for Lustre, and AWS ParallelCluster accelerate global R&D innovation.

Optimize your compute costs

At AWS, we focus on delivering the best possible cost structure for our customers. Frugality is one of our founding leadership principles. Cost effective design continues to shape everything we do, from how we develop products to how we run our operations. Come learn new ways to optimize your compute costs through AWS services, tools, and optimization strategies in the following sessions:

CMP347 | The Frugal Architect in a chaotic world

Discover the practical implementation of Werner Vogels’ Frugal Architect principles through a hands-on exploration of AWS Graviton, EC2 Spot, Karpenter, and AI tools. Watch as we optimize a shopping cart using AI and flame graphs, demonstrating how to build efficient systems without compromising quality. Learn to combine Karpenter’s intelligent scaling, the performance benefits of AWS Graviton, and AI-driven analysis to create systems that are faster, leaner, and more cost-effective by design.

CMP349 | 5-Star customer service: Duolingo’s path to compute savings

Learn how Duolingo partnered with their AWS Technical Account Manager to transform their cloud spending. Discover their successful transition to AWS Graviton processors, from initial cost analysis through enterprise-wide implementation. Observe how the AWS customer-focused approach delivered significant savings and business value for Duolingo.

CMP337 | Optimizing EC2: Hands-on strategies for cost-effective performance

Get hands-on with advanced EC2 instance optimization in this technical workshop. Learn to analyze workloads, measure performance metrics, and master benchmarking tools through guided exercises. Walk away with practical strategies to choose and tune EC2 instances for your specific application needs. Perfect for architects and developers looking to maximize their AWS infrastructure performance.

CMP314 | Data-driven EC2 optimization: Efficiency, metrics, and sustainability

Join this chalk talk to discover how metric-driven decisions can transform your EC2 fleet optimization. Through real-world scenarios, learn to analyze workload data, choose optimal instance types, and fine-tune capacity for your specific needs. We explore practical approaches to balance cost, performance, and sustainability using AWS-native tools, providing you with actionable strategies that you can implement immediately.

CMP412 | EC2 Flex instances: Get the latest generation performance at lower costs

Explore how EC2 Flex instances deliver the latest generation performance at reduced costs. Learn about optimal workload types, architectural design, and implementation strategies. Discover practical approaches to adoption and performance monitoring to maximize your EC2 Flex instance benefits.

Maximize your workload’s performance

Your workload’s performance matters beyond just cost because it directly impacts the quality, efficiency, and effectiveness of your compute solution. It can significantly influence customer satisfaction, business growth, and overall productivity. Even if a cheaper option exists, a low-cost option with poor performance can lead to long-term financial losses due to issues such as lost customers, engineering rework, and negative reputation. We have several sessions that help you optimize your workload’s performance.

CMP333 | Maximizing EC2 performance: A hands-on guide to instance optimization

Live coding session: Learn to optimize EC2 performance using Amazon CloudWatch and APerf. Observe real-world examples of workload analysis and code optimization across different instance types and programming languages.

CMP351 | Building for efficiency and reliability with performance testing on AWS

Learn performance testing strategies on AWS to optimize costs, identify bottlenecks, and improve reliability. Discover how to measure system behavior under various loads to inform architecture and instance selection decisions.

CMP405 | Everything you’ve wanted to know about performance on EC2 instances

Explore compute optimization techniques in this code talk. Learn about memory topology, hardware counters, hyperthreading effects, and methods for accurate performance testing and latency optimization.

Customer experience and applications with AI and ML

ML has been evolving for decades and has an inflection point with generative AI applications capturing widespread attention and imagination. Learn about generative AI infrastructure at Amazon or get hands-on experience building ML applications through our ML focused sessions, such as the following:

CMP201 | Architecting solution patterns for GPU-accelerated HPC and AI/ML

Interactive discussion on GPU-accelerated HPC and AI/ML architecture. Explore EC2 GPU instance families, architectural tradeoffs , and cost optimization strategies. Share your challenges and learn how to build scalable GPU solutions on AWS.

CMP403 | Build, scale, and optimize agentic AI on CPUs with AWS Graviton

Hands-on workshop: Build cost-efficient AI applications on AWS Graviton. Deploy large language model (LLM) inference, multi-agent systems, and vector databases using Amazon Elastic Kubernetes Service (Amazon EKS) and Karpenter. Create a chat app showcasing the performance benefits of AWS Graviton.

CMP346 | Supercharge ML and inference on Apple Silicon with EC2 Mac

Learn to optimize ML workloads on EC2 Mac instances with Apple silicon. Explore Apple Neural Engine, Core ML, and efficient PyTorch/TensorFlow deployment for iOS and cloud ML applications.

CMP338 | Protect privacy in generative AI applications using AWS Confidential Computing

Build three secure generative AI applications while learning to protect sensitive data in prompts, augmented sources, and model weights. Practice implementing AWS Confidential Computing features in EC2 to mitigate common security threats. Get hands-on experience using both open source models and Amazon Bedrock to create privacy-first AI solutions.

CMP410 | Secure generative AI using trusted execution environments

Hands-on session: Build a secure AI environment using Nitro TPM-enabled EC2 instances. Deploy an LLM with cryptographic attestation and learn to protect sensitive data using trusted execution environments.

Accelerate your AWS Graviton adoption journey

The AWS Graviton Processors are custom designed server processors designed by AWS. They deliver the best price performance for your cloud workloads running in AWS and help you reduce your carbon footprint. Ready to realize up to 40% better price performance for your workloads? We have curated the following session to help you accelerate your AWS Graviton adoption:

CMP329 | Learnings from developers adopting AWS Graviton at scale

Learn how the custom-designed AWS Graviton processors deliver optimal price-performance across diverse workloads: from microservices to HPC. Engage with AWS experts to explore adoption strategies, best practices, and real customer success stories for scaling AWS Graviton in production.

CMP352 | Unlock cost efficiency with AWS Graviton Savings Dashboard

Discover how the enhanced AWS Graviton Savings Dashboard provides deeper analytics for workload modernization, enabling up to 40% better price performance. Learn to use advanced features for granular workload analysis and streamlined migration planning. This lightning talk shows you how to transform efficiency insights into actionable strategies for measurable cloud cost savings.

CMP326 | Java modernization and performance optimization GameDay

Hands-on workshop: Use Amazon Q Developer to modernize Java applications from v8 to v21. Practice automated code analysis, performance benchmarking, and cost optimization across different instances. Laptop needed.

CMP335 | Optimize .NET TCO with agentic AI powered AWS Transform and AWS Graviton

Hands-on workshop: Use agentic AI to accelerate the migration of Windows-based .NET applications to .NET Core running on Linux with AWS Graviton for 40% better price performance. Learn code analysis, automated transformations, and CI/CD updates. For .NET developers/architects. Laptop needed.

Optimizing your container-based workloads

Maximizing the efficiency of container-based workloads is crucial for modern cloud applications. Whether you’re running microservices, web applications, or high-performance computing tasks, optimizing your container infrastructure can significantly impact both performance and cost. In this track, we’ve assembled essential sessions focused on using AWS Graviton processors and modernization tools to enhance your containerized applications. From real-world adoption stories to hands-on workshops, these sessions can help you achieve better price performance while maintaining operational excellence. Join us to explore the following:

CMP310 | Boost Amazon EKS efficiency: Amazon EKS Auto Mode, AWS Graviton, and EC2 Spot

Explore how Amazon EKS Auto Mode streamlines Kubernetes operations by removing infrastructure management complexity. Learn to optimize costs using AWS Graviton and EC2 Spot, with practical examples for building more efficient, cost-effective container environments.

CMP311 | Build once, run everywhere: Multi-architecture in your CI/CD pipelines

Learn to build multi-architecture containers for x86 and AWS Graviton processors. Observe how to optimize web applications for both platforms and integrate with CI/CD systems such as ArgoCD, GitLab, and GitHub.

CMP348 | Using Amazon Q to cost optimize your containerized workloads

Learn to achieve 40% better price-performance by migrating containerized workloads to AWS Graviton using Amazon EKS and Karpenter. Use Amazon Q to accelerate x86-to-Graviton migration, implement multi-architecture CI/CD pipelines, and optimize deployment strategies.

Quantum computing

Quantum computing is moving from theoretical possibility to practical reality, offering groundbreaking potential across industries. As organizations prepare for this technology, AWS provides the tools and infrastructure needed to explore quantum applications today. Through Amazon Braket, our managed quantum computing service, we’re making quantum experimentation accessible to enterprises, researchers, and developers alike. Whether you’re interested in drug discovery, optimization problems, or cybersecurity, this track offers a comprehensive journey from quantum basics to advanced hybrid solutions. Join industry leaders, such as AstraZeneca and Accenture, to discover how quantum computing is already delivering value and how you can begin your quantum journey:

CMP202 | Amazon Braket: Get hands-on with quantum computing

Get started with quantum computing in this practical workshop. Learn to implement quantum algorithms and run circuits on gate-based devices using Amazon Braket. Explore the quantum algorithm library of AWS through hands-on exercises. Bring your laptop to begin your quantum journey.

CMP209 | Amazon Braket hubs: Accelerating R&D in national quantum initiatives

Learn how AWS supports quantum computing research hubs worldwide, helping create secure environments and providing access to cutting-edge quantum technologies for researchers and startups.

CMP411 | Quantum computing with Amazon Braket: From exploration to enterprise

Explore quantum computing with Amazon Braket, featuring the AWS strategy and AstraZeneca’s drug discovery research. Learn how to combine quantum and classical workloads and prepare for future quantum technologies.

CMP205 | Q-CTRL Fire Opal on Amazon Braket: Quantum solutions from security to finance

Learn how organizations use Q-CTRL and Amazon Braket for quantum computing breakthroughs. Observe how Accenture Federal Services achieved 3x better network security detection using Q-CTRL’s optimizer, and explore quantum-classical solutions for various industries.

CMP304 | Architectures for hybrid quantum-classical workflows at scale

Learn to build hybrid quantum-classical computing solutions using Amazon Braket with AWS services (AWS Batch, AWS ParallelCluster) and GPU-accelerated instances. Explore architectures integrating CPUs, GPUs, and quantum processors using NVIDIA CUDA-Q.

Check out workload-specific sessions

EC2 offers the broadest and deepest compute platform to help you best match the needs of your workload. Join sessions focused on your specific workload to learn about how you can use AWS solutions to accelerate your innovations.

CMP207 | Startup to scale: Powering business growth with Amazon Lightsail

Get started in the cloud with just a few clicks with Amazon Lightsail. Discover how it can support your business at any stage of growth. Whether you’re launching your first cloud workload, migrating existing applications, or managing services for your customers, learn proven approaches for success. We explore how customers are using Lightsail today, including cost optimization and best practices for efficient scaling.

CMP320 | Full stack web apps on EC2: Using AWS Elastic Beanstalk with Amazon Q

Accelerate your cloud journey with AWS Elastic Beanstalk and Amazon Q. Learn how Elastic Beanstalk streamlines deployment and maintenance of full stack web applications on EC2 with automated infrastructure provisioning, while Amazon Q enhances your Elastic Beanstalk experience with natural language commands, intelligent troubleshooting guidance, and deployment best practices recommendations. This is perfect for teams ready to focus on building exceptional applications instead of managing infrastructure.

CMP334 | Modernize Apple platform development with AWS and EC2 Mac

Explore how EC2 Mac instances enable scalable, cost-effective macOS workloads on AWS. Learn about the latest features and hear a customer success story showcasing optimized Apple development workflows in the cloud.

CMP341 | SAP workloads on memory optimized Amazon EC2 instances

Discover how the memory-optimized instances (R, X, U) of EC2 revolutionize SAP HANA deployments, eliminating traditional infrastructure compromises. Learn from SAP’s experience managing RISE with SAP on AWS, and explore how high-memory instances can transform your SAP operations.

CMP319 | Exploring the spectrum of architecture patterns for 3D rendering

Explore the complete rendering toolkit of AWS for 3D and spatial applications: from GPU-powered EC2 instances to distributed rendering with Deadline Cloud and real-time GameLift Streams. Learn practical architecture patterns and cost optimization strategies to scale your rendering pipeline for games, architectural visualization, and AR/VR experiences.

CMP321 | Generative AI storyboarding: From Sketch to 3D Scene with generative AI on AWS

Learn to create visual content using Amazon Bedrock: convert sketches to storyboards, generate 2D/3D assets, and compose scenes. Explore AI-assisted workflows for film, games, and UI design while maintaining artistic control.

CMP211 | Hybrid science: AI + physics simulations for climate and life sciences

Explore how to combine AI with physics simulations using AWS services (such as AWS Batch, AWS ParallelCluster, Amazon FSx, EFA). Learn real-world patterns for integrating AI and simulation workflows in climate, weather, and healthcare applications.

CMP345 | Accelerate drug discovery R&D at scale with AWS

Interactive session on how top pharma companies use AWS for drug discovery R&D. Explore solutions for imaging, molecular simulation, and AI-driven research, with focus on managing large-scale data and diverse compute needs.

CMP350 | Accelerating vehicle innovation: ML and HPC best practices

Learn how Toyota and Deloitte transformed automotive engineering by migrating HPC and ML workloads to AWS. Using NVIDIA GPUs and EC2 HPC instances, they dramatically reduced development cycles. You can gain practical insights for your own high-performance computing initiatives.

CMP401 | Accelerating semiconductor design, simulation, and verification on AWS

This session covers the latest compute and storage innovations such as the new generation of EC2 instances powered by custom Intel Xeon Scalable processors (Granite Rapids), AMD EPYC processors (Turin), and AWS Graviton, and new features of Amazon FSx for NetApp ONTAP.

CMP406 | HPC infrastructure for financial services using AWS Batch and AWS CDK

Hands-on session: Build HPC infrastructure using AWS Cloud Development Kit (AWS CDK). Deploy AWS Batch for financial risk analysis workloads. This is suitable for HPC experts new to AWS and AWS developers new to HPC.

CMP204 | Quantum computing: Accelerating pharma innovation

Explore how Merck Sharp & Dohme partners with MathWorks and AWS to revolutionize pharmaceutical development through quantum computing. Using MATLAB and Amazon Braket, they implement QAOA for optimizing drug production and enhancing cancer diagnostics.

Ready to unlock new possibilities?

The AWS Compute team looks forward to seeing you in Las Vegas. Come meet us at the Compute Booth in the Expo and check out our various EC2 demos. And if you’re looking for more session recommendations, check-out more re:Invent attendee guides curated by experts.
Secure EKS clusters with the new support for Amazon EKS in AWS Backup

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/secure-eks-clusters-with-the-new-support-for-amazon-eks-in-aws-backup/

Today, we’re announcing support for Amazon EKS in AWS Backup to provide the capability to secure Kubernetes applications using the same centralized platform you trust for your other Amazon Web Services (AWS) services. This integration eliminates the complexity of protecting containerized applications while providing enterprise-grade backup capabilities for both cluster configurations and application data. AWS Backup is a fully managed service to centralize and automate data protection across AWS and on-premises workloads. Amazon Elastic Kubernetes Service (Amazon EKS) is a fully managed Kubernetes service to manage availability and scalability of the Kubernetes clusters. With this new capability, you can centrally manage and automate data protection across your Amazon EKS environments alongside other AWS services.

Until now, for backups, customers relied on custom solutions or third-party tools to back up their EKS clusters, requiring complex scripting and maintenance for each cluster. The support for Amazon EKS in AWS Backup eliminates this overhead by providing a single, centralized, and policy-driven solution that protects both EKS clusters (Kubernetes deployments and resources) and stateful data (stored in Amazon Elastic Block Store (Amazon EBS), Amazon Elastic File System (Amazon EFS), and Amazon Simple Storage Service (Amazon S3) only) without the need to manage custom scripts across clusters. For restores, customers were previously required to restore their EKS backups to a target EKS cluster which was either the source EKS cluster, or a new EKS cluster, requiring that an EKS cluster infrastructure is provisioned ahead of time prior to the restore. With this new capability, during a restore of EKS cluster backups, customers also have the option to create a new EKS cluster based on previous EKS cluster configuration settings and restore to this new EKS cluster, with AWS Backup managing the provisioning of the EKS cluster on the customer’s behalf.

This support includes policy-based automation for protecting single or multiple EKS clusters. This single data protection policy provides a consistent experience across all services AWS Backup supports. It allows creation of immutable backups to prevent malicious or inadvertent changes, helping customers meet their regulatory compliance needs. In case there is a customer data loss or cluster downtime event, customers can easily recover their EKS cluster data from encrypted, immutable backups using an easy-to-use interface and maintain business continuity of running their EKS clusters at scale.

How it works
Here’s how I set up support for on-demand backup of my EKS cluster in AWS Backup. First, I’ll show a walkthrough of the backup process, then demonstrate a restore of the EKS cluster.

Backup
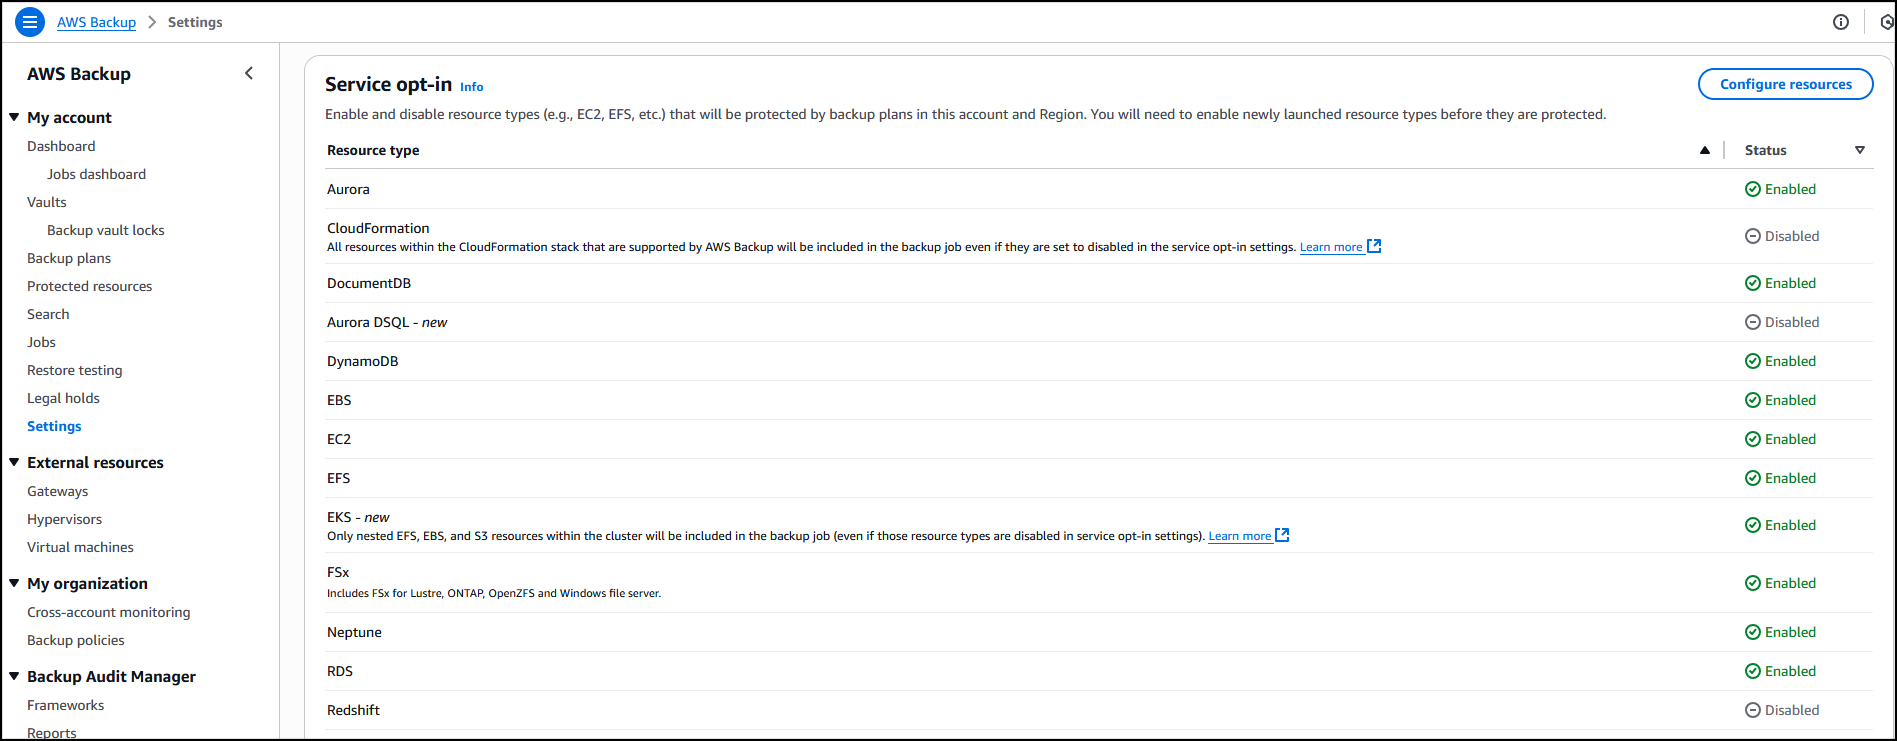
In the AWS Backup console, in the left navigation pane, I choose Settings and then Configure resources to opt in to enable protection of EKS clusters in AWS Backup.

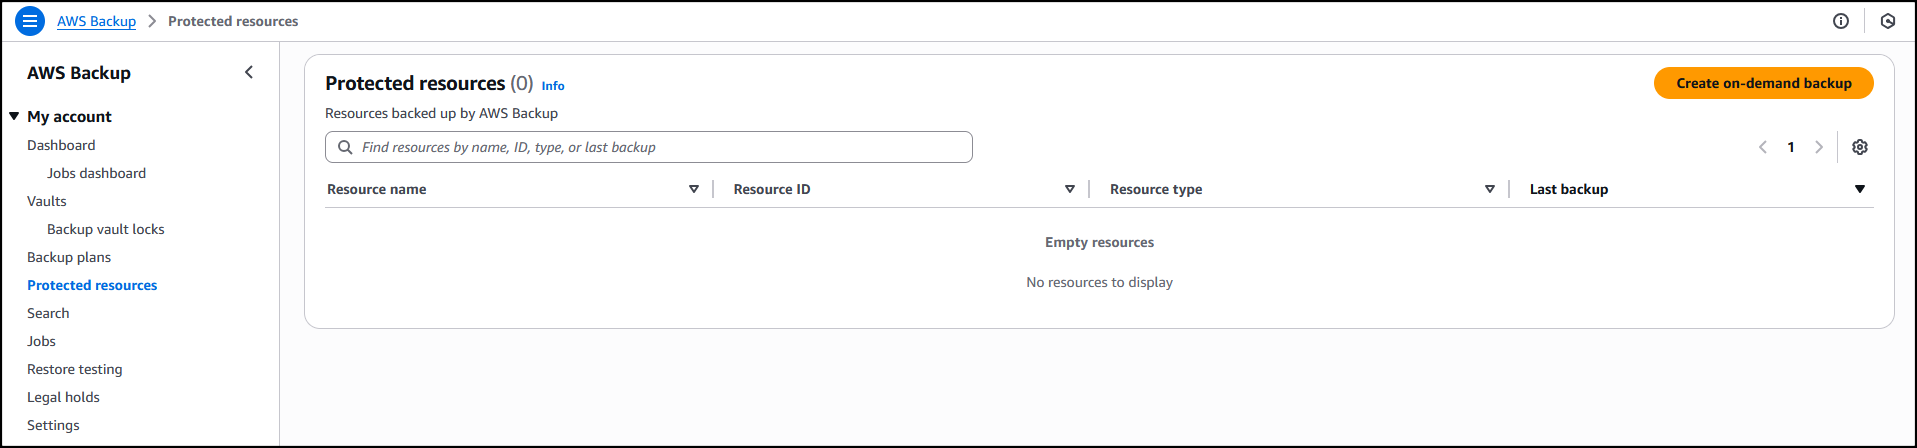
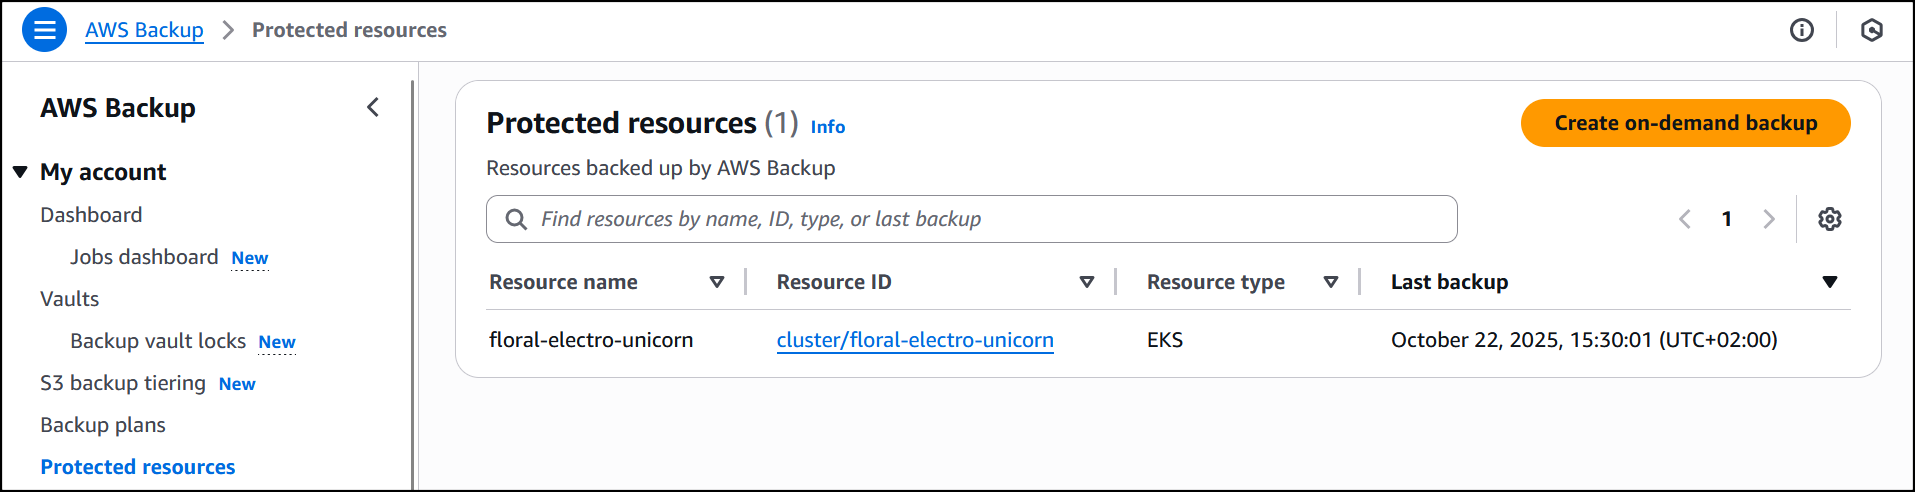
Now that I’ve enabled Amazon EKS, in Protected resources I choose Create on-demand backup to create a backup for my already existing EKS cluster floral-electro-unicorn.

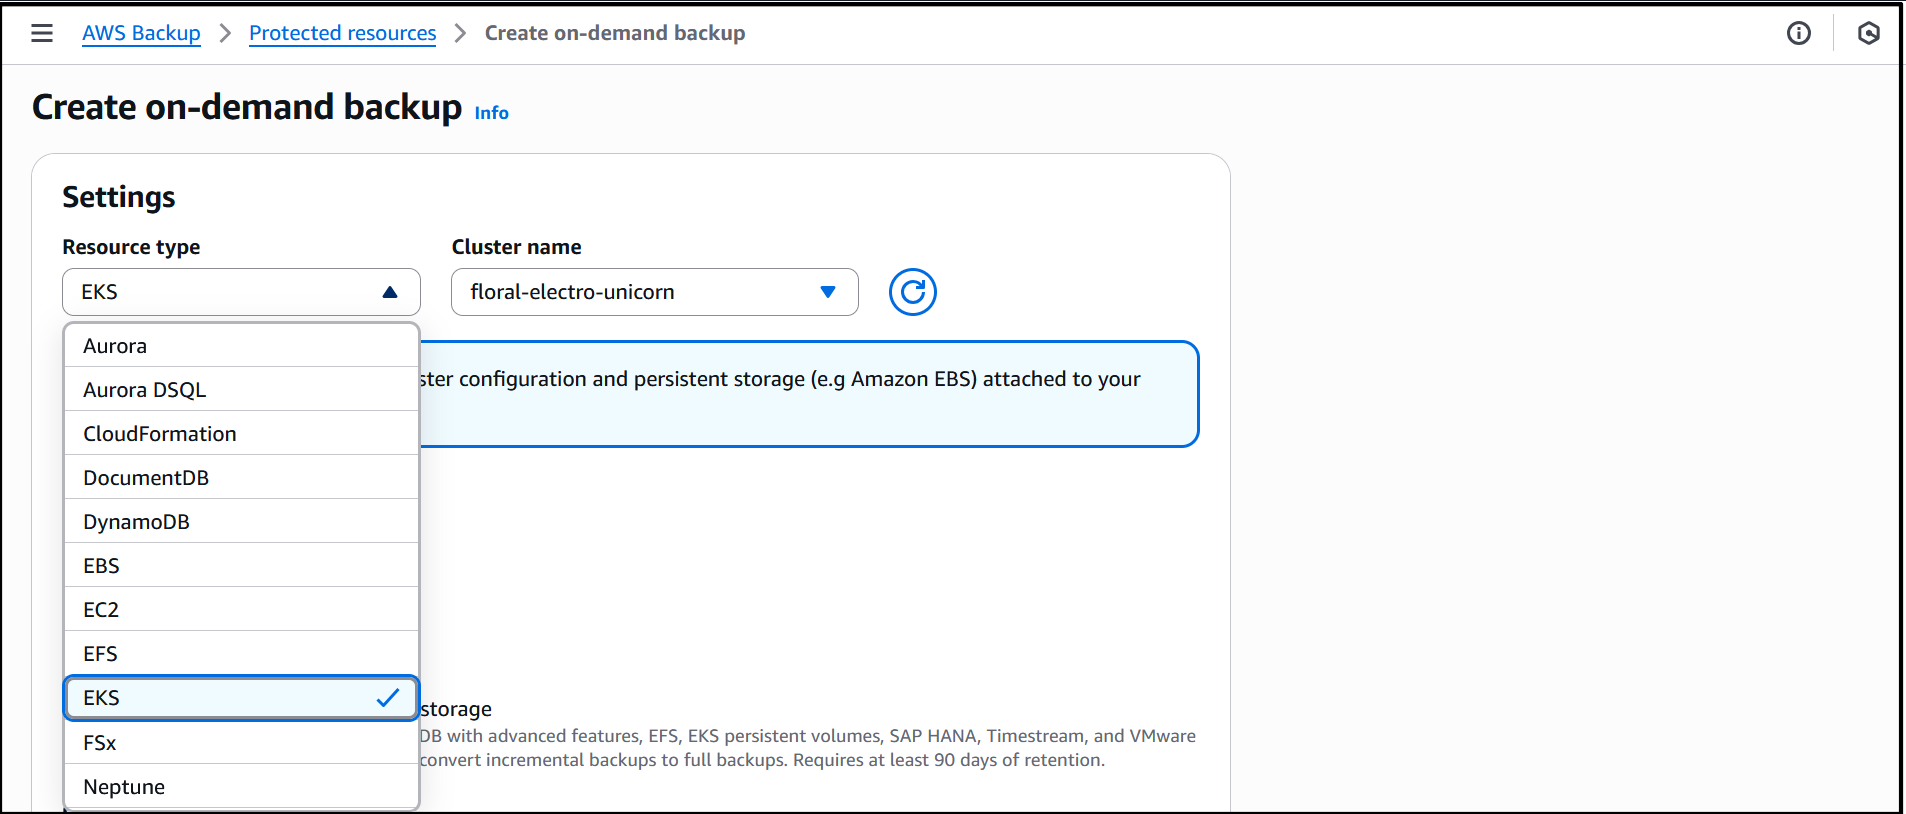
Enabling EKS in Settings ensures that it shows up as a Resource type when I create on-demand backup for the EKS cluster. I proceed to select the EKS resource type and the cluster.

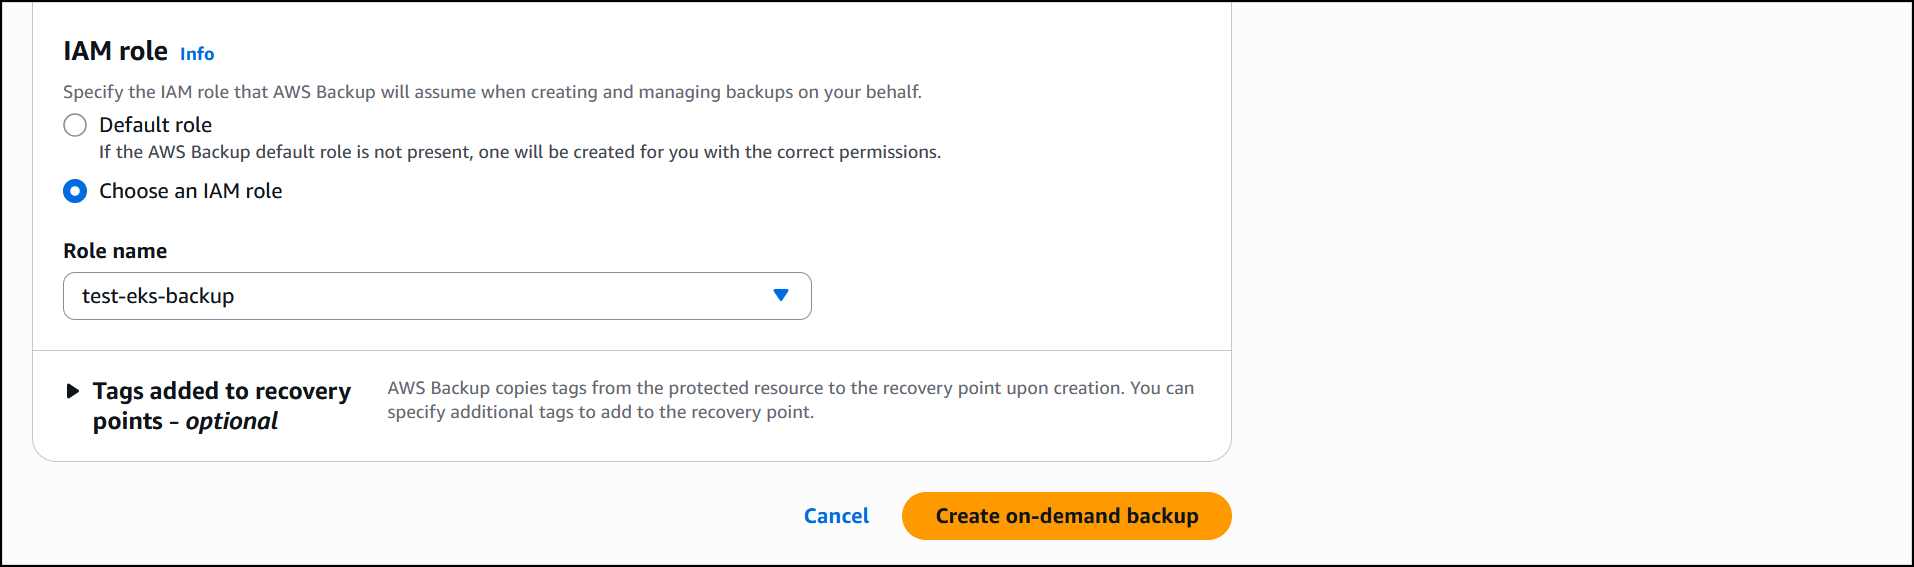
I leave the rest of the information as default, then select Choose an IAM role to select a role (test-eks-backup) that I’ve created and customized with the necessary permissions for AWS Backup to assume when creating and managing backups on my behalf. I choose Create on-demand backup to finalize the process.


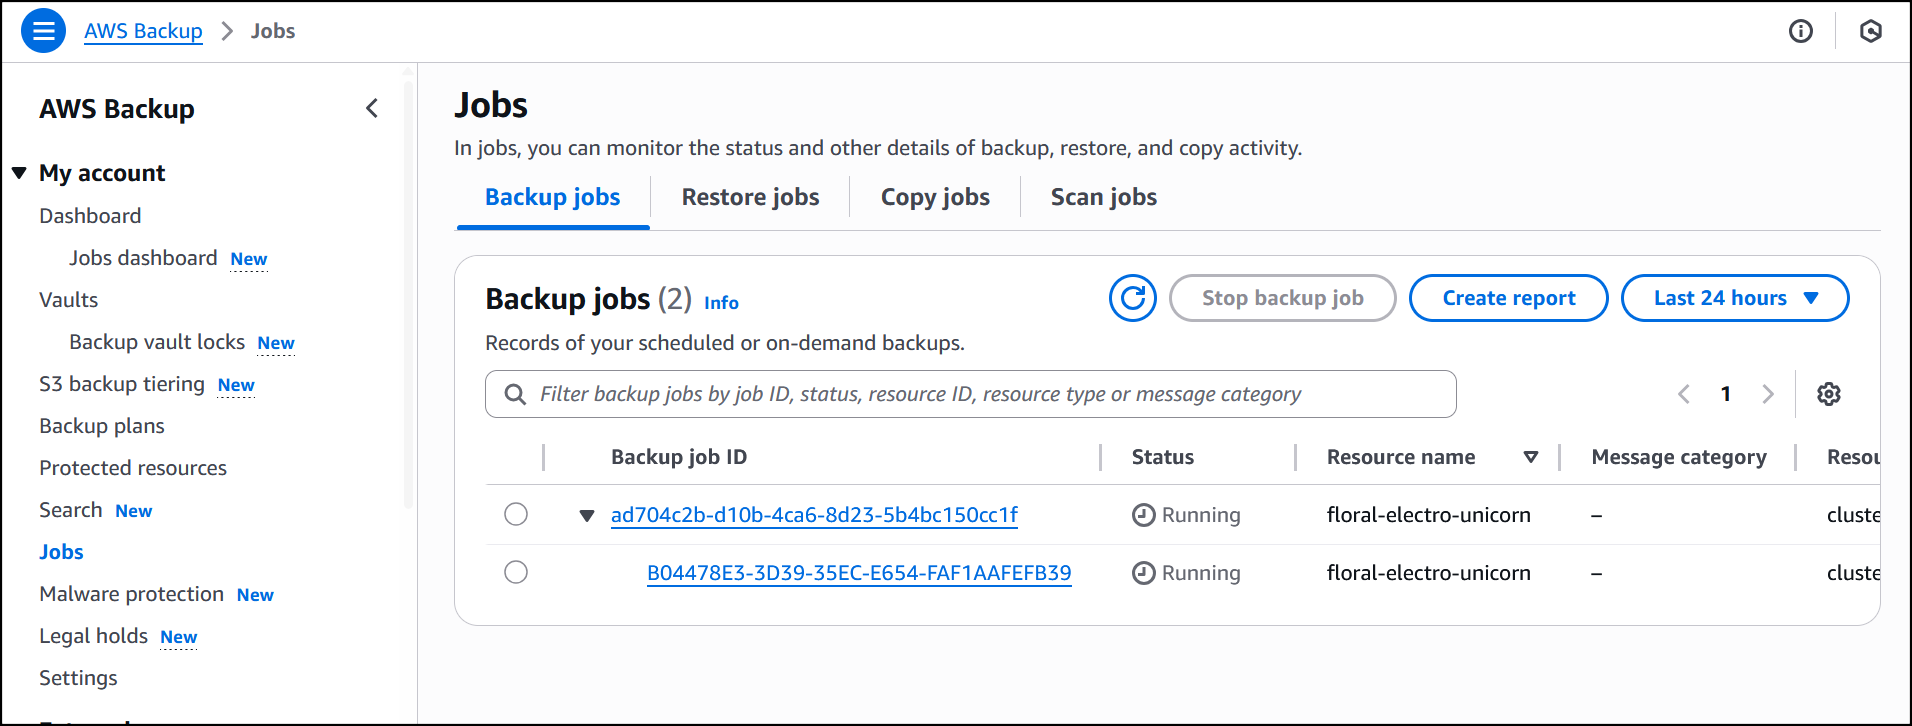
The job is initiated, and it will start running to back up both the EKS cluster state and the persistent volumes. If Amazon S3 buckets are attached to the backup, you’ll need to add the additional Amazon S3 backup permissions AWSBackupServiceRolePolicyForS3Backup to your role. This policy contains the permissions necessary for AWS Backup to back up any Amazon S3 bucket, including access to all objects in a bucket and any associated AWS KMS key.


The job is completed successfully and now EKS clusterfloral-electro-unicorn is backed up by AWS Backup.


Restore
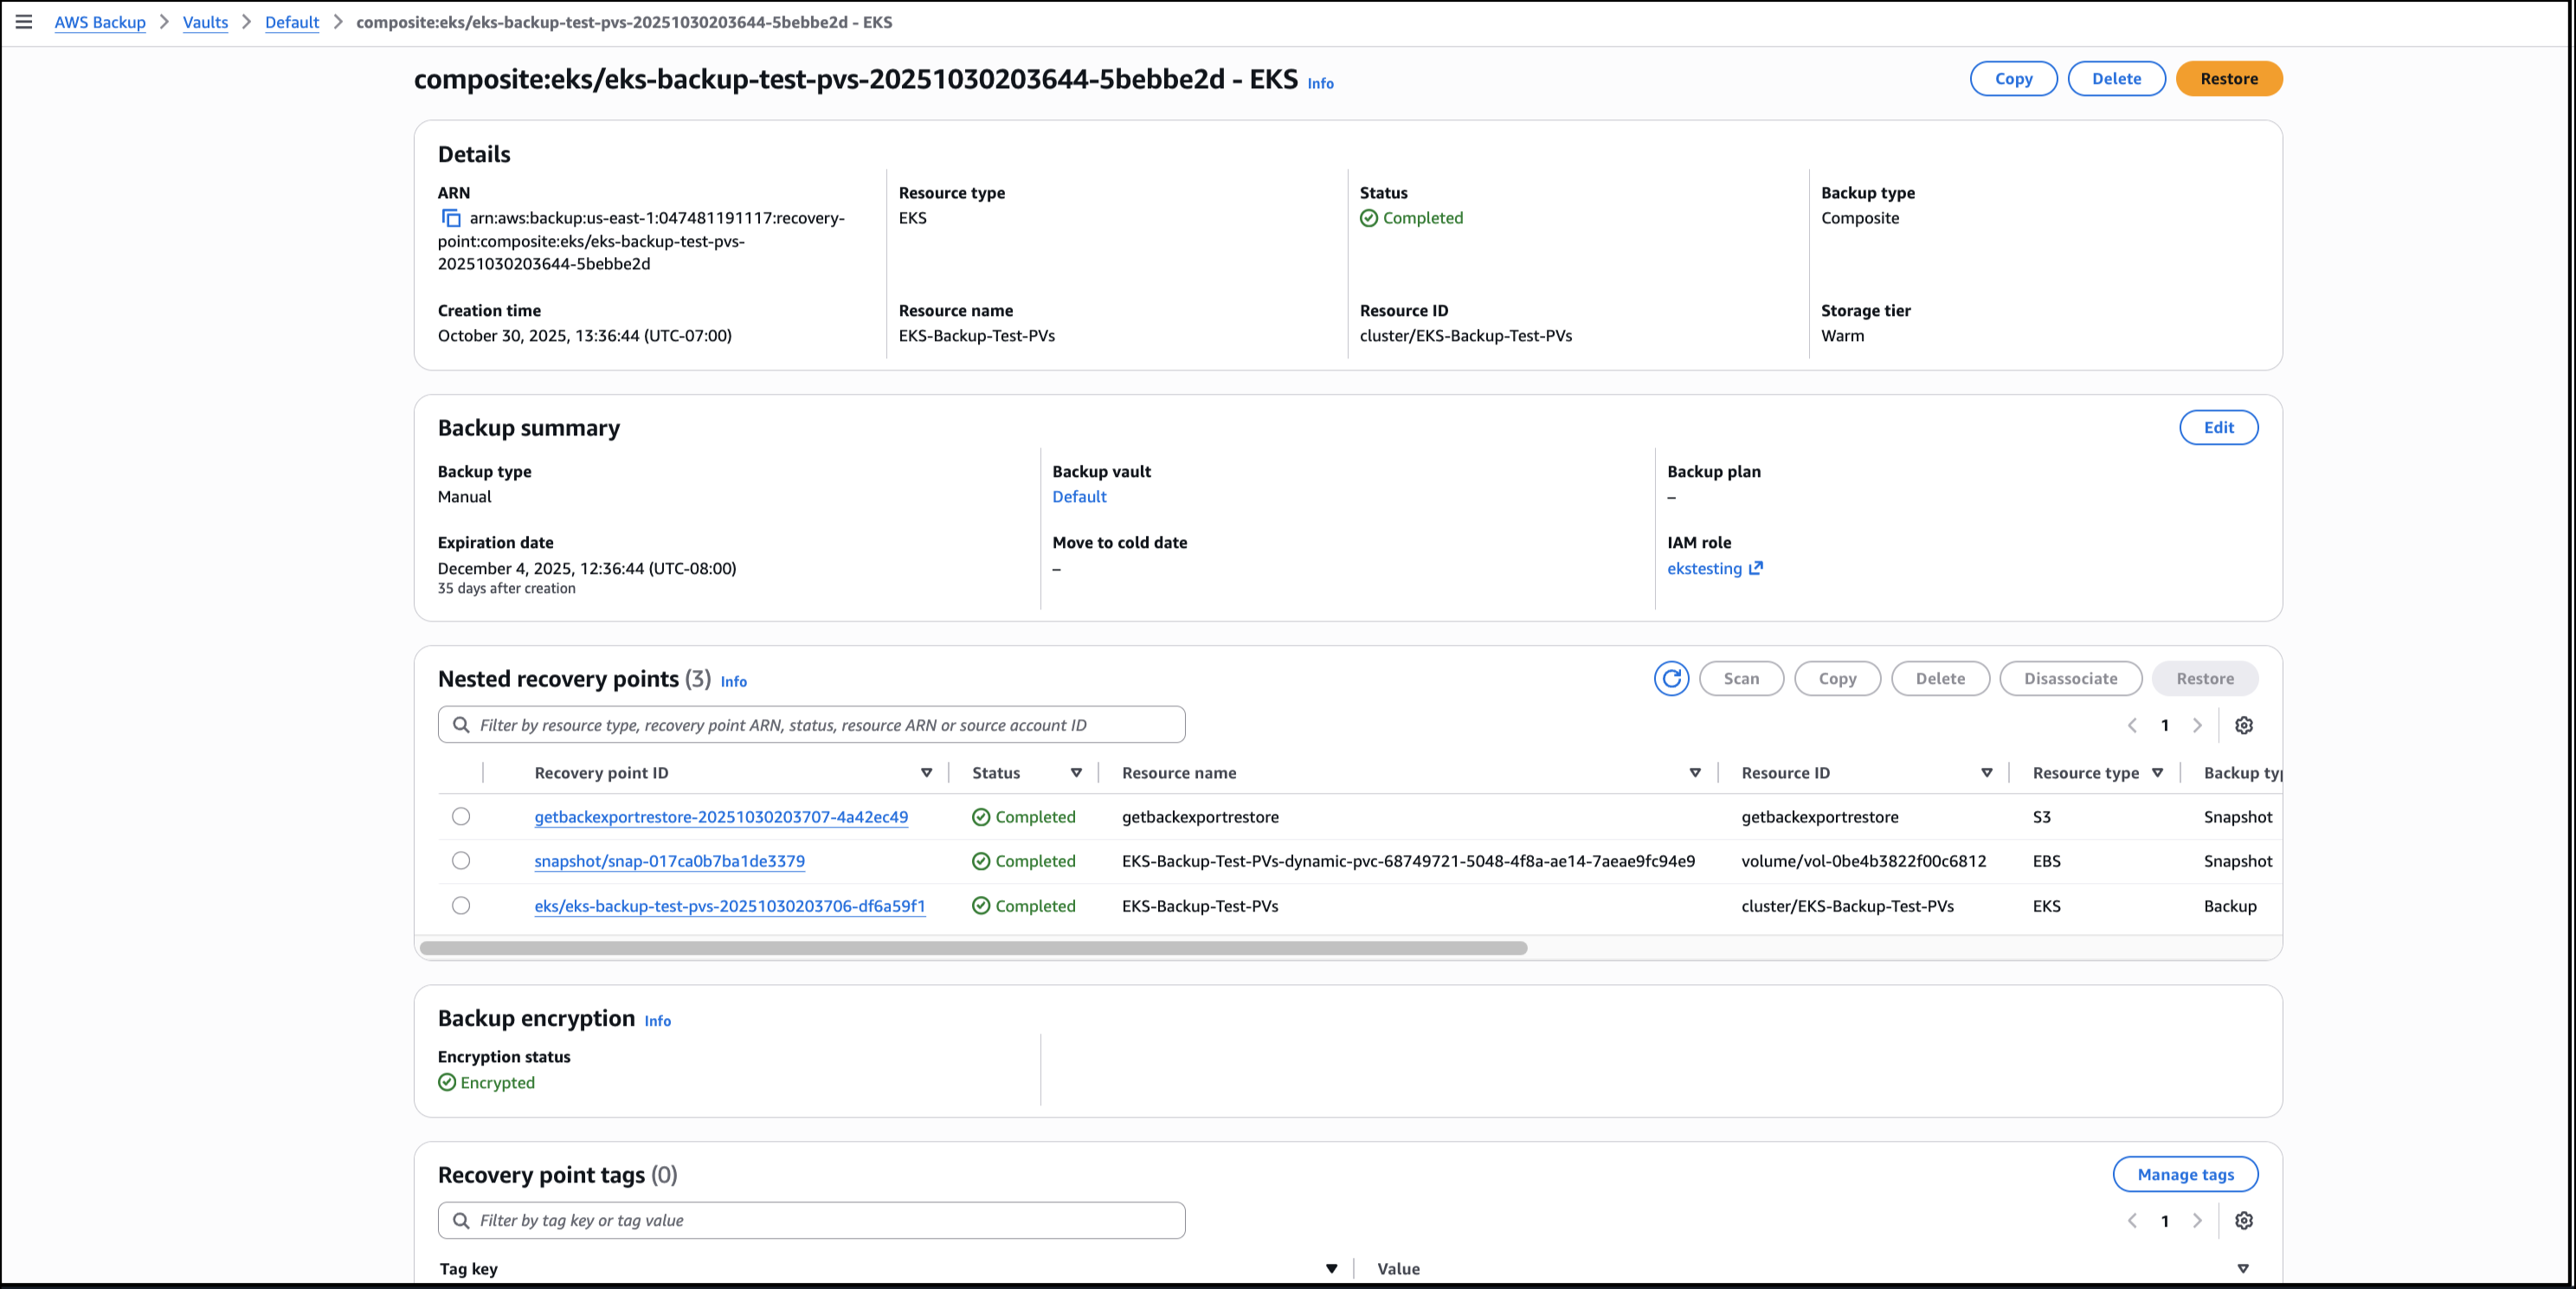
Using the AWS Backup Console, I choose the EKS backup composite recovery point to start the process of restoring the EKS cluster backups, then choose Restore.


I choose Restore full EKS cluster to restore the full EKS backup. To restore to an existing cluster, I Choose an existing cluster then select the cluster from the drop-down list. I choose the Default order as the order in which individual Kubernetes resources will be restored.

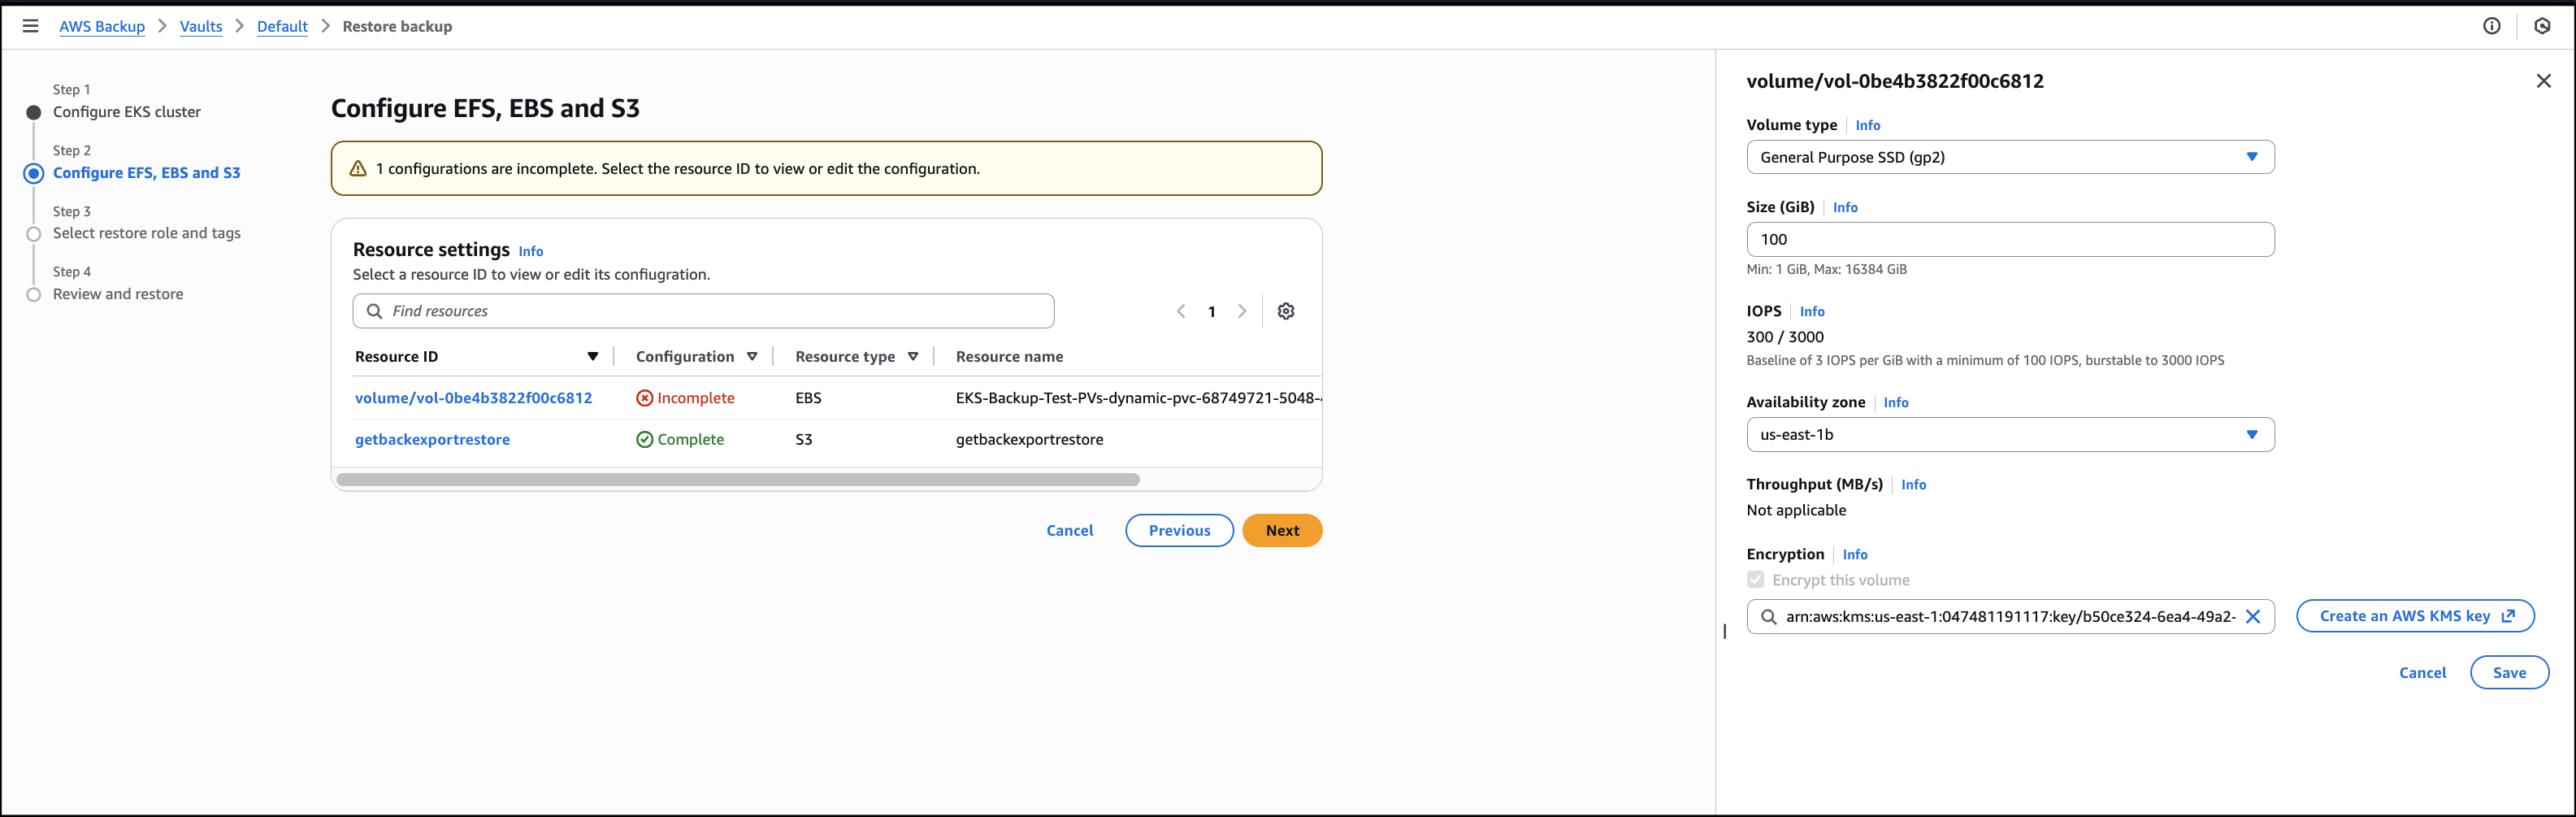
I then configure the restore for the persistent storage resources, that will be restored alongside my EKS clusters.


Next, I Choose an IAM role to execute the restore action. The Protected resource tags checkbox is selected by default and I’ll leave it as is, then choose Next.

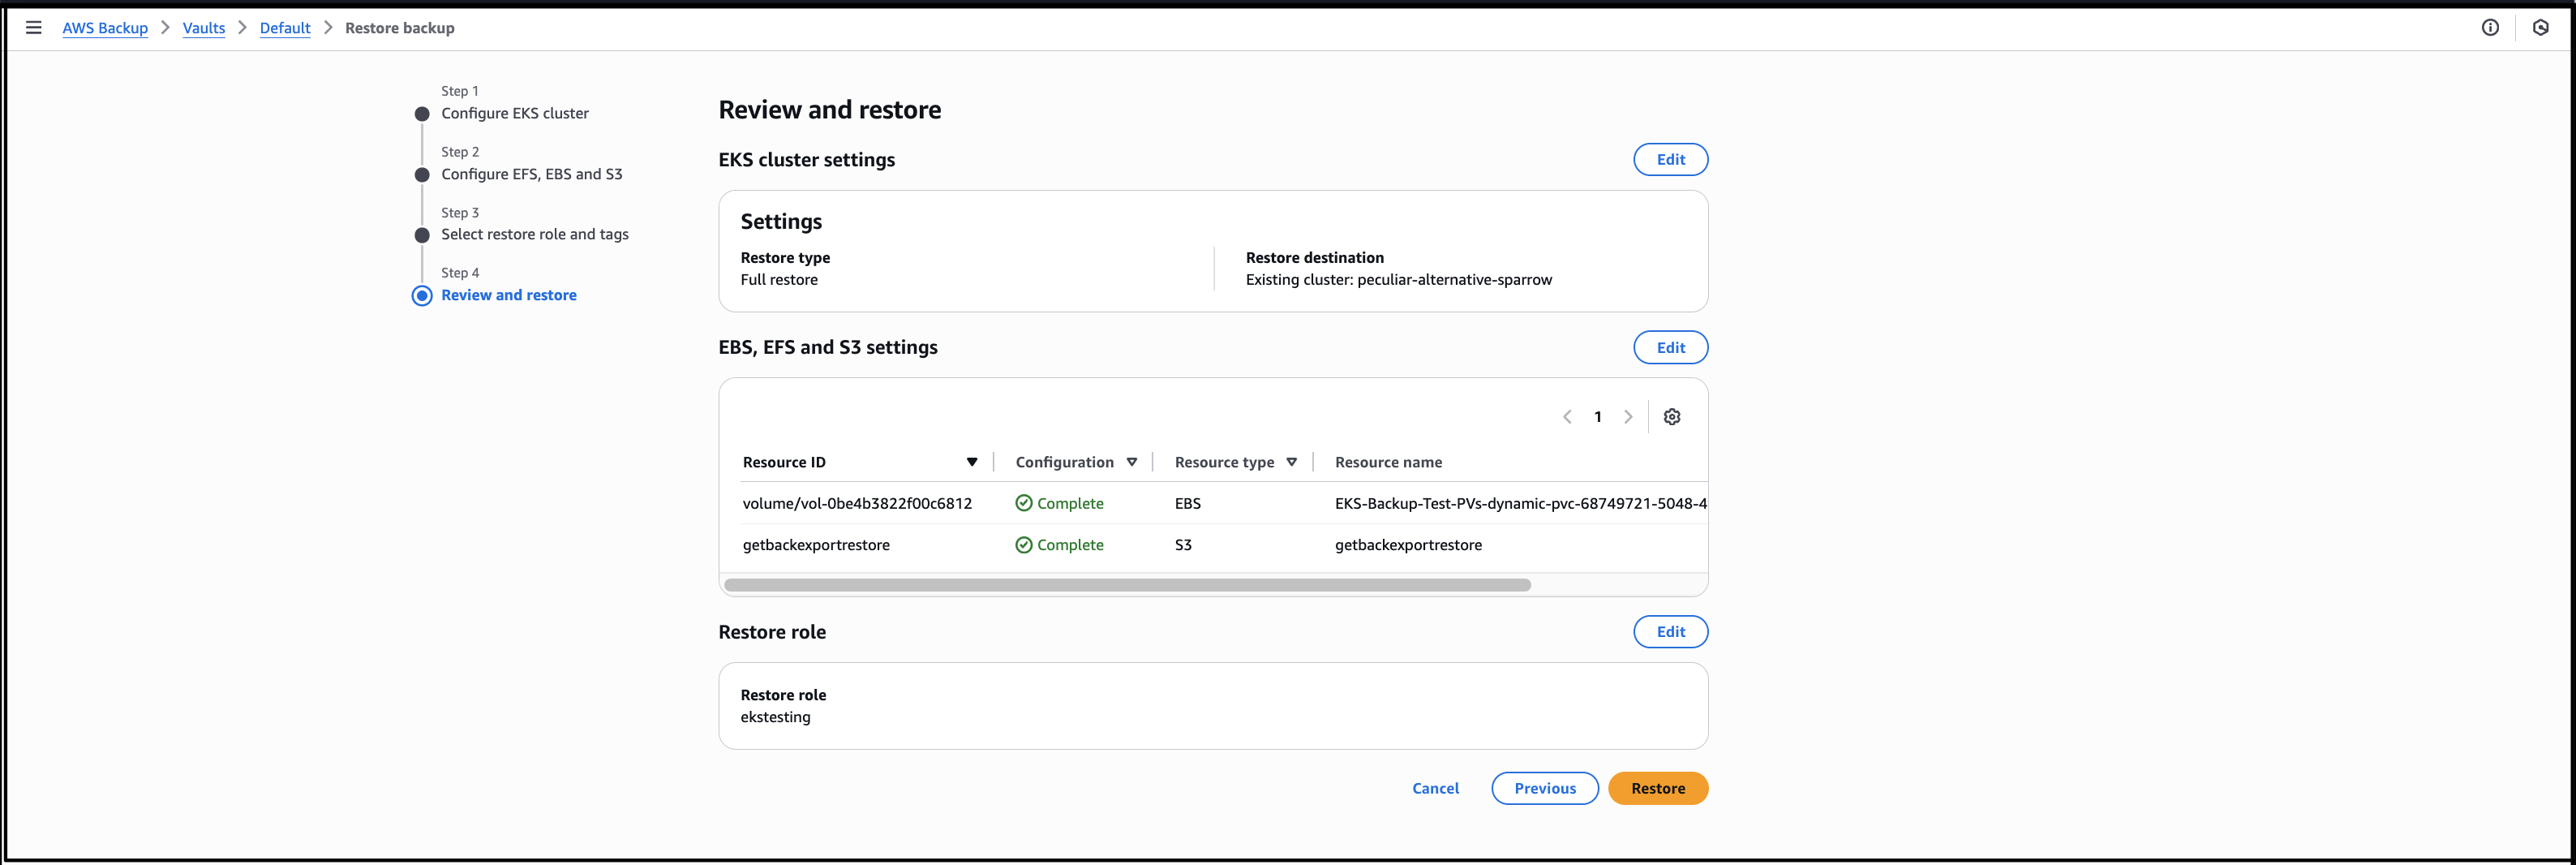
I review all the information before I finalize the process by choosing Restore, to start the job.


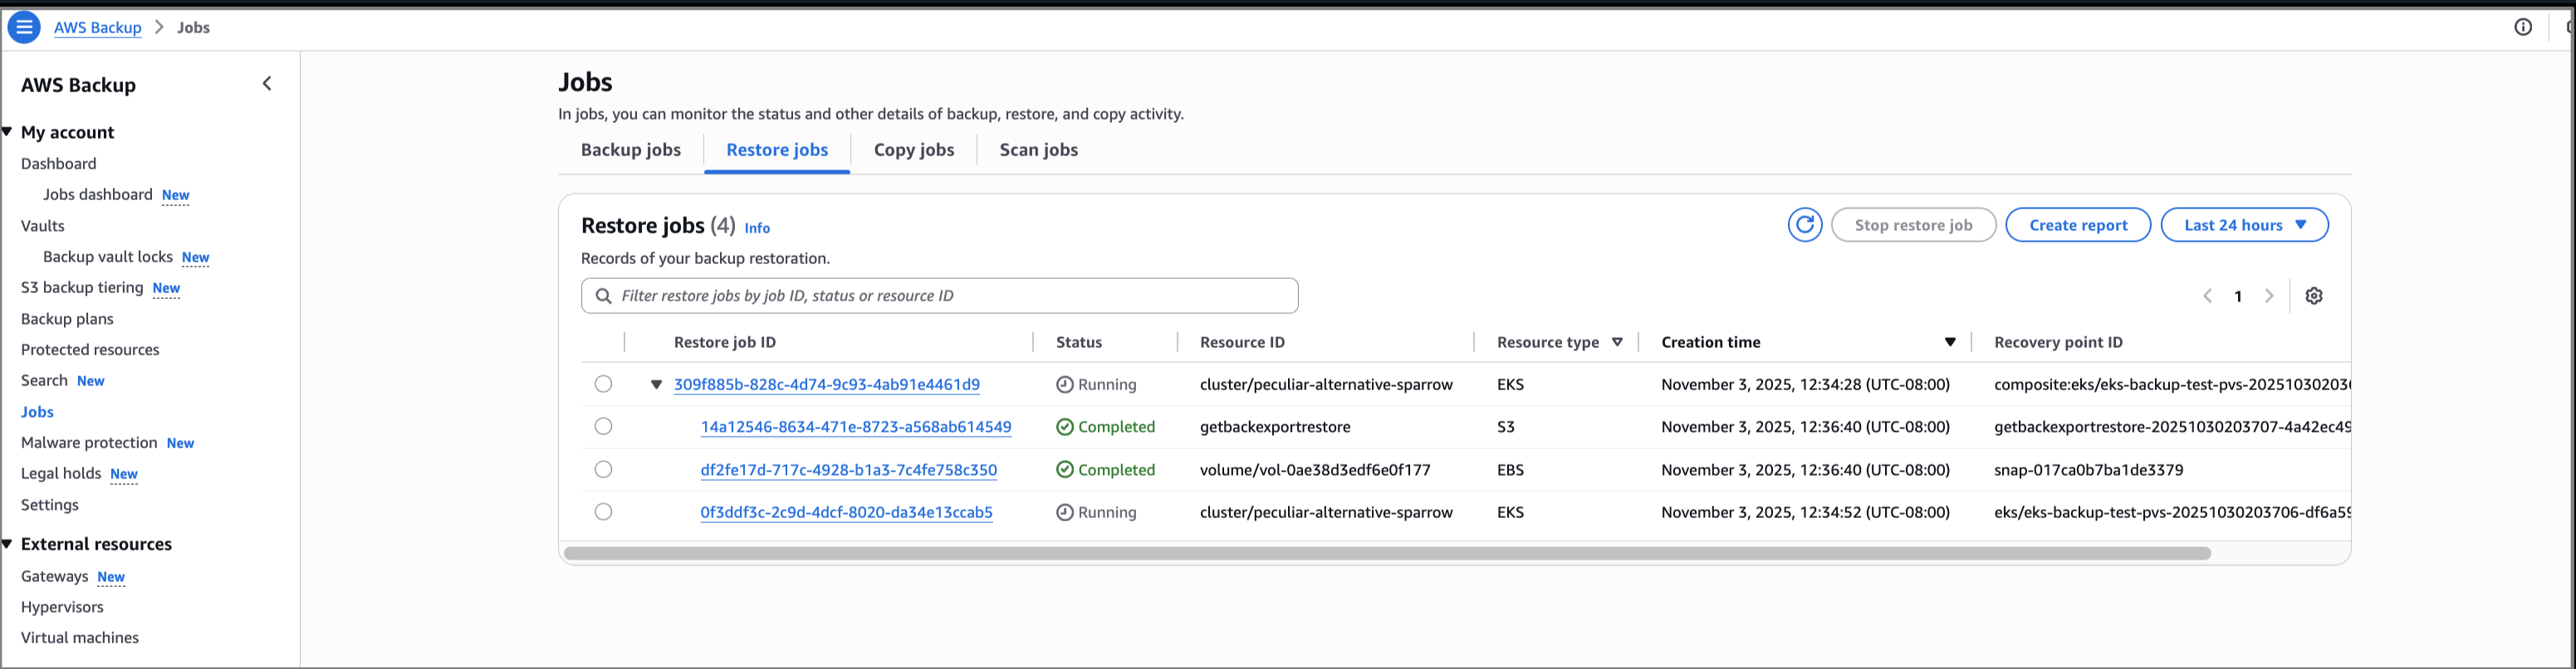
Selecting the drop-down arrow gives details of the restore status for both the EKS cluster state and persistent volumes attached. In this walkthrough, all the individual recovery points are restored successfully. If portions of the backup fail, it’s possible to restore the successfully backed up persistent stores (for example, Amazon EBS volumes) and cluster configuration settings individually. However, it’s not possible to restore full EKS backup. The successfully backed up resources will be available for restore, listed as nested recovery points under the EKS cluster recovery point. If there’s a partial failure, there will be a notification of the portion(s) that failed.


Benefits
Here are some of the benefits provided by the support for Amazon EKS in AWS Backup:

  • A fully managed multi-cluster backup experience, removing the overhead associated with managing custom scripts and third-party solutions.
  • Centralized, policy-based backup management that simplifies backup lifecycle management and makes it seamless to back up and recover your application data across AWS services, including EKS.
  • The ability to store and organize your backups with backup vaults. You assign policies to the backup vaults to grant access to users to create backup plans and on-demand backups but limit their ability to delete recovery points after they’re created.

Good to know
The following are some helpful facts to know:

  • Use either the AWS Backup Console, API, or AWS Command Line Interface (AWS CLI) to protect EKS clusters using AWS Backup. Alternatively, you can create an on-demand backup of the cluster after it has been created.
  • You can create secondary copies of your EKS backups across different accounts and AWS Regions to minimize risk of accidental deletion.
  • Restoration of EKS backups is available using the AWS Backup Console, API, or AWS CLI.
  • Restoring to an existing cluster will not override the Kubernetes versions, or any data as restores are non-destructive. Instead, there will be a restore of the delta between the backup and source resource.
  • Namespaces can only be restored to an existing cluster to ensure a successful restore as Kubernetes resources may be scoped at the cluster level.

Voice of the customer

Srikanth Rajan, Sr. Director of Engineering at Salesforce said “Losing a Kubernetes control plane because of software bugs or unintended cluster deletion can be catastrophic without a solid backup and restore plan. That’s why it’s exciting to see AWS rolling out the new EKS Backup and Restore feature, it’s a big step forward in closing a critical resiliency gap for Kubernetes platforms.”

Now available
Support for Amazon EKS in AWS Backup is available today in all AWS commercial Regions (except China) and in the AWS GovCloud (US) where AWS Backup and Amazon EKS are available. Check the full Region list for future updates.

To learn more, check out the AWS Backup product page and the AWS Backup pricing page.

Try out this capability for protecting your EKS clusters in AWS Backup and let us know what you think by sending feedback to AWS re:Post for AWS Backup or through your usual AWS Support contacts.

Veliswa.

BASF Digital Farming builds a STAC-based solution on Amazon EKS

Post Syndicated from Kevin S. Ridolfi original https://aws.amazon.com/blogs/architecture/basf-digital-farming-builds-a-stac-based-solution-on-amazon-eks/

This post was co-written with Frederic Haase and Julian Blau with BASF Digital Farming GmbH.

At xarvio – BASF Digital Farming, our mission is to empower farmers around the world with cutting-edge digital agronomic decision-making tools. Central to this mission is our crop optimization platform, xarvio FIELD MANAGER, which delivers actionable insights through a range of geospatial assets, including satellite imagery, drone data, and application maps from sprayers.

In this post, we show you how we built a scalable geospatial data solution on AWS to efficiently catalog, manage, and visualize both raster and vector datasets through the web. We walk you through our solution based on the SpatioTemporal Asset Catalog (STAC) specification and the open source eoAPI ecosystem, detailing the solution architecture, key technologies, and lessons learned during deployment. This builds upon a previous post on efficient satellite imagery ingestion using AWS Serverless, extending our discussion to the full lifecycle of geospatial data management at scale.

Requirements for our geospatial data solution

BASF Digital Farming’s xarvio FIELD MANAGER platform operates at exceptional scale in the geospatial data ecosystem, processing hundreds of millions of satellite images that translate into STAC items, which further decompose into billions of individual geospatial artifacts. Unlike traditional satellite data providers such as European Space Agency (ESA) who work with predictable, structured data flows, we operate in an inherently dynamic agricultural environment where we ingest near-daily satellite imagery per field from a diverse array of sensors and providers globally. Our mission to support farmers worldwide with advanced digital agronomic decision advice demands a reliable, cloud-based infrastructure capable of handling this massive data velocity and volume and applying advanced quality assurance processes including cloud detection and anomaly detection algorithms. The platform’s true value emerges through our machine learning (ML) pipelines that transform raw satellite data into actionable insights. For example, estimating accurate absolute biomass such as Leaf Area Index (LAI) helps farmers make precise, data-driven agronomic decisions that optimize crop yield and resource utilization across fields worldwide.

STAC and eoAPI ecosystem

To efficiently manage our growing archive of geospatial data, we adopted the Spatio Temporal Asset Catalog (STAC) specification, an open standard that provides a common language to describe and catalog raster and vector datasets. With STAC, we can standardize metadata across diverse sources like satellite imagery, UAV datasets, and prescription maps, making it straightforward to search, filter, and retrieve assets across our platform. We built our platform using the eoAPI ecosystem, an integrated suite of open source tools designed to handle the full lifecycle of geospatial data on the cloud. At its core is pgSTAC, which provides a performant PostGIS-backed STAC API implementation. With pgSTAC, we can index millions of STACi Items efficiently, with support for spatial, temporal, and attribute-based filtering at scale. On top of that, we use Tiles in PostGIS (TiPG) to serve tiled vector data directly from our PostGIS database. This enables real-time visualization of field boundaries, management zones, and application histories as lightweight Mapbox Vector Tiles (MVT), without requiring an external tile server. For raster assets, including satellite and drone imagery, we rely on TiTiler, a modern dynamic tile server built for Cloud Optimized GeoTIFFs (COGs). With TiTiler, we can stream imagery on-demand as WMTS or XYZ tiles, perform dynamic rendering (such as NDVI or false color composites), and integrate seamlessly into web maps and mobile apps.

Solution overview

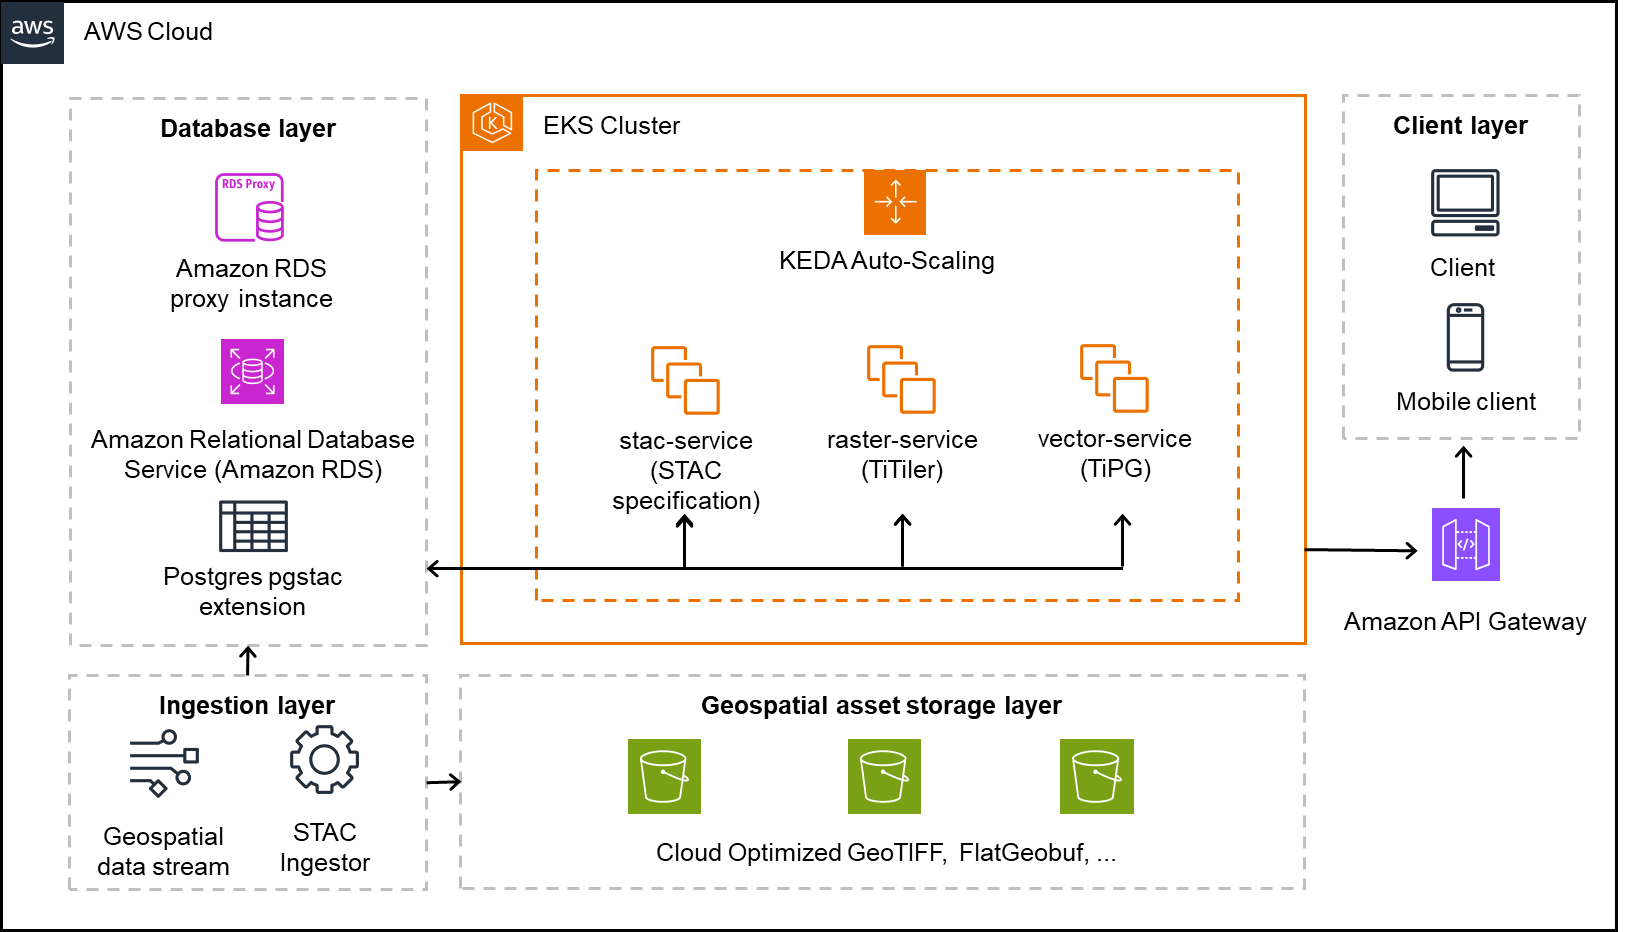
The following architecture diagram shows how we implemented our geospatial data platform on AWS. In this section, we explain each component of the architecture and how they work together to process millions of satellite images and geospatial assets daily. The solution uses Amazon Elastic Kubernetes Service (Amazon EKS) as the core computing platform, with Amazon Simple Storage Service (Amazon S3) for storage and Amazon Relational Database Service (Amazon RDS) for metadata management. We break down the architecture into four main layers: core services, storage, database, and ingestion.

A detailed AWS Cloud architecture visualization showcasing a complete geospatial data processing system across four distinct layers. The database layer features an EKS Cluster managing STAC, raster, and vector services, all connected to Amazon RDS through a proxy instance. The client layer supports both desktop and mobile access via Amazon API Gateway. The ingestion layer processes geospatial data streams through a STAC ingestor, feeding into a robust storage layer utilizing Cloud Optimized GeoTIFF and FlatGeobuf technologies. The architecture emphasizes scalability and efficient spatial data handling through PostgreSQL with pgstac extension, enabling seamless integration of various geospatial services and data formats.

Core services layer

The solution uses an EKS cluster hosting three key services:

  • stac-service – Implements the STAC API specification to catalog and serve metadata for both raster and vector datasets
  • raster-service – Powered by TiTiler, this service dynamically renders and tiles cloud-optimized raster data (for example, COGs) for seamless integration into web and mobile maps
  • vector-service – Built with TiPG, this component serves vector data (for example, boundaries or application zones) as tiled MVT layers directly from the database or from Amazon S3

These services are containerized and orchestrated within Kubernetes, allowing for high availability, modular separation, and simplified continuous integration and delivery (CI/CD) workflows.

KEDA-based automatic scaling

We use Kubernetes Event-Driven Autoscaling (KEDA) to scale our platform services dynamically based on real-time workloads. With KEDA, we can scale individual pods based on precise event-driven metrics such as the STAC ingestion queue depth or visualization request load. This supports responsive performance during peak activity while maintaining lean resource usage during idle periods, aligning perfectly with our need for elasticity in a data-intensive, variable-load environment.

Geospatial asset storage layer

The platform stores all raw and processed geospatial assets in S3 buckets, optimized for performance and durability. This layer holds COGs for raster imagery and FlatGeobuf or similar formats for vector data. These formats are chosen for their support of streaming access, indexing, and cloud-based performance.

Database layer

The metadata backbone of the system is a PostgreSQL database hosted on Amazon RDS, extended with the pgSTAC plugin. This setup enables efficient indexing and querying of millions of STAC items and collections. An RDS proxy sits in front of the database, providing connection pooling and resiliency, especially under bursty or concurrent access patterns common in geospatial applications.

Ingestion layer

An independent ingestion component handles batch or streaming geospatial data inputs. This component processes satellite imagery, drone data, or prescription maps and pushes relevant metadata into the STAC API and storage assets into Amazon S3. The ingestion engine is decoupled from serving infrastructure, enabling asynchronous and large-scale data loading.

Amazon API Gateway and clients

Public access to the platform is handled through Amazon API Gateway, allowing clients—whether browser-based or mobile—to interact securely with the services. The API gateway provides a unified entrypoint and is used for applying rate limiting, authorization, and routing policies.

Solution benefits

The solution offers the following benefits:

  • Rapid onboarding with STAC standardization – By aligning with the STAC specification, we’ve significantly reduced the time to onboard new data domains like sprayer application maps. Compared to previous approaches in our legacy system, metadata modeling and integration are now both standardized and automated, so we can expose new geospatial data products to clients in days instead of weeks or months.
  • Optimized storage with COGs and Amazon S3 – Storing raster and vector assets in Amazon S3 using cloud-optimized formats (such as COGs for imagery or FlatGeobuff for vectors) reduces storage costs while enabling low-latency, streaming access. This avoids the need for preprocessing or extract, transform, and load (ETL)-heavy pipelines and simplifies client delivery.
  • Large-scale ingestion with a batch STAC ingestor – Our custom STAC ingestor supports both real-time and batch-mode operations. This has made it possible to onboard satellite constellations, drone imagery, and historical datasets in bulk without disrupting running services. The ingestion service uses optimized database ingestion functions, capable of ingesting thousands of items per second, providing high-throughput and reliable data integration at scale.
  • PostgreSQL, pgSTAC, and Amazon RDS Proxy for a scalable metadata backbone – With pgSTAC and Amazon RDS Proxy, we benefit from advanced spatial-temporal querying while making sure database connection management is handled gracefully, even under high concurrency. This combination offers reliability without compromising performance.
  • Scalable deployment with Amazon EKS – Hosting the solution on Amazon EKS provides full control over deployments, resource tuning, and service orchestration. Combined with automatic scaling, we dynamically adjust compute capacity based on demand, facilitating resilience and cost-efficiency.

Learnings

As part of building this solution, we learned the following:

  • RDS Proxy is essential for automatically scaled environments – Given our use of automatic scaling pods in Amazon EKS, we found that RDS Proxy is critical. It handles connection pooling efficiently and protects the underlying PostgreSQL database from connection exhaustion during sudden scale-up events. Without it, we encountered spiky load failures and blocked connections during high-ingest periods.
  • Batch STAC ingestor is a core component – Our custom STAC ingestor proved to be an indispensable piece of the system. It interfaces directly with pgSTAC to perform large-scale, automated ingestions of geospatial metadata from streams and archives. Without this tool, onboarding data providers or processing legacy imagery at scale would have been labor-intensive and error-prone.
  • COGs are non-negotiable – For fast, scalable visualization of large raster datasets, COGs are essential, particularly if raster datasets exceed several gigabytes. They enable efficient HTTP range requests, alleviate the need for preprocessing, and work seamlessly with TiTiler for real-time tile rendering. Non-COG formats led to noticeably slower performance and weren’t suitable for cloud-based visualization.
  • Serverless-compliant, optimized for Amazon EKS (for now) – Although the architecture is designed to be serverless-compatible, we opted for an Amazon EKS first approach due to the nature of our other application landscape. Components like TiTiler and TiPG benefit from persistent, memory-tuned environments that are harder to achieve in a serverless runtime. However, the solution remains modular and stateless by design, and certain subsystems (such as ingestion triggers, notifications, or monitoring) are already candidates for future serverless migration to further improve elasticity and reduce operational overhead.

Conclusion

BASF Digital Farming GmbH has successfully implemented a STAC-based geospatial data platform on Amazon EKS, enabling efficient management and visualization of satellite imagery, drone data, and application maps. This architecture helps us onboard new data sources within weeks rather than months. The new platform also processes twice as much data in a single day while cutting costs by 50%, thanks to reduced data handling through the STAC schema and the efficiencies of automatic scaling. By adopting the STAC standard, the architecture improves data discoverability, reduces search latency, and supports more efficient analytic workflows.

Organizations looking to build similar geospatial data solutions can use AWS services like Amazon EKS, Amazon S3, and Amazon RDS along with open source tools like STAC and eoAPI to create scalable, cost-effective solutions. Learn more about building containerized applications on AWS at Containers on AWS.

AWS Weekly Roundup: Kiro waitlist, EBS Volume Clones, EC2 Capacity Manager, and more (October 20, 2025)

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-kiro-waitlist-ebs-volume-clones-ec2-capacity-manager-and-more-october-20-2025/

I’ve been inspired by all the activities that tech communities around the world have been hosting and participating in throughout the year. Here in the southern hemisphere we’re starting to dream about our upcoming summer breaks and closing out on some of the activities we’ve initiated this year. The tech community in South Africa is participating in Amazon Q Developer coding challenges that my colleagues and I are hosting throughout this month as a fun way to wind down activities for the year. The first one was hosted in Johannesburg last Friday with Durban and Cape Town coming up next.

Last week’s launches
These are the launches from last week that caught my attention:

Additional updates
I thought these projects, blog posts, and news items were also interesting:

Upcoming AWS events
Keep a look out and be sure to sign up for these upcoming events:

AWS re:Invent 2025 (December 1-5, 2025, Las Vegas) — AWS flagship annual conference offering collaborative innovation through peer-to-peer learning, expert-led discussions, and invaluable networking opportunities.

Join the AWS Builder Center to learn, build, and connect with builders in the AWS community. Browse here for upcoming in-person and virtual developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

Veliswa.

New general-purpose Amazon EC2 M8a instances are now available

Post Syndicated from Betty Zheng (郑予彬) original https://aws.amazon.com/blogs/aws/new-general-purpose-amazon-ec2-m8a-instances-are-now-available/

Today, we’re announcing the availability of Amazon Elastic Compute Cloud (Amazon EC2) M8a instances, the latest addition to the general-purpose M instance family. These instances are powered by the 5th Generation AMD EPYC (codename Turin) processors with a maximum frequency of 4.5GHz. Customers can expect up to 30% higher performance and up to 19% better price performance compared to M7a instances. They also provide higher memory bandwidth, improved networking and storage throughput, and flexible configuration options for a broad set of general-purpose workloads.

Improvements in M8a
M8a instances deliver up to 30% better performance per vCPU compared to M7a instances, making them ideal for applications that require benefit from high performance and high throughput such as financial applications, gaming, rendering, application servers, simulation modeling, midsize data stores, application development environments, and caching fleets.

They provide 45% more memory bandwidth compared to M7a instances, accelerating in-memory databases, distributed caches, and real-time analytics.

For workloads with high I/O requirements, M8a instances provide up to 75 Gbps of networking bandwidth and 60 Gbps of Amazon Elastic Block Store (Amazon EBS) bandwidth, a 50% improvement over the previous generation. These enhancements support modern applications that rely on rapid data transfer and low-latency network communication.

Each vCPU on an M8a instance corresponds to a physical CPU core, meaning there is no simultaneous multithreading (SMT). In application benchmarks, M8a instances delivered up to 60% faster performance for GroovyJVM and up to 39% faster performance for Cassandra compared to M7a instances.

M8a instances support instance bandwidth configuration (IBC), which provides flexibility to allocate resources between networking and EBS bandwidth. This gives customers the flexibility to scale network or EBS bandwidth by up to 25% and improve database performance, query processing, and logging speeds.

M8a is available in ten virtualized sizes and two bare metal options (metal-24xl and metal-48xl), providing deployment choices that scale from small applications to large enterprise workloads. All of these improvements are built on the AWS Nitro System, which delivers low virtualization overhead, consistent performance, and advanced security across all instance sizes. These instances are built using the latest sixth generation AWS Nitro Cards, which offload and accelerate I/O for functions, increasing overall system performance.

M8a instances feature sizes of up to 192 vCPU with 768GiB RAM. Here are the detailed specs:

M8a vCPUs Memory (GiB) Network bandwidth (Gbps) EBS bandwidth (Gbps)
medium 1 4 Up to 12.5 Up to 10
large 2 8 Up to 12.5 Up to 10
xlarge 4 16 Up to 12.5 Up to 10
2xlarge 8 32 Up to 15 Up to 10
4xlarge 16 64 Up to 15 Up to 10
8xlarge 32 128 15 10
12xlarge 48 192 22.5 15
16xlarge 64 256 30 20
24xlarge 96 384 40 30
48xlarge 192 768 75 60
metal-24xl 96 384 40 30
metal-48xl 192 768 75 60

For a complete list of instance sizes and specifications, refer to the Amazon EC2 M8a instances page.

When to use M8a instances
M8a is a strong fit for general-purpose applications that need a balance of compute, memory, and networking. M8a instances are ideal for web and application hosting, microservices architectures, and databases where predictable performance and efficient scaling are important.

These instances are SAP certified and also well suited for enterprise workloads such as financial applications and enterprise resource planning (ERP) systems. They’re equally effective for in-memory caching and customer relationship management (CRM), in addition to development and test environments that require cost efficiency and flexibility. With this versatility, M8a supports a wide spectrum of workloads while helping customers improve price performance.

Now available
Amazon EC2 M8a instances are available today in US East (Ohio) US West (Oregon) and Europe (Spain) AWS Regions. M8a instances can be purchased as On-Demand, Savings Plans, and Spot Instances. M8a instances are also available on Dedicated Hosts. To learn more, visit the Amazon EC2 Pricing page.

To learn more, visit the Amazon EC2 M8a instances page and send feedback to AWS re:Post for EC2 or through your usual AWS support contacts.

Betty

DISA STIG for Amazon Linux 2023 is now available

Post Syndicated from Mahak Arora original https://aws.amazon.com/blogs/compute/disa-stig-for-amazon-linux-2023-is-now-available/

Today, we announce the availability of a Security Technical Implementation Guide (STIG) for Amazon Linux 2023 (AL2023), developed through collaboration between Amazon Web Services (AWS) and the Defense Information Systems Agency (DISA). The STIG guidelines are important for U.S Department of Defense (DOD) and Federal customers needing strict security compliance derived from the National Institute of Standards and Technology (NIST) 800-53 and related documents. This new technical implementation guide provides detailed Operating System (OS) security hardening configurations for organizations deploying AL2023 in DOD environments and other agencies requiring DISA STIG alignment. The AL2023 STIG provides customers with access to an OS guide that complies with stringent government security standards. This guide for implementing STIG configurations will streamline security processes for organizations seeking robust cybersecurity controls, whether they are needed to maintain DOD compliance or voluntarily adopting these best security practices to enhance their security posture.

Implementing the AL2023 DISA STIG with AWS

AWS Systems Manager (SSM) and EC2 Image builder offer native solutions for implementing the AL2023 DISA STIG configurations in your environment. For customers with existing AL2023 EC2 workload, they can utilize AWS Systems Manger (SSM) to streamline the STIG implementation. For customers who would like to build STIG compliant AL2023 EC2 instances to use for deployment, they can utilize EC2 Image Builder and automate the application of the AL2023 DISA STIG.

Customers can utilize EC2 Image builder to enhance and streamline their implementation of the AL2023 DISA STIG. This integrated approach significantly reduces the operational overhead traditionally associated with maintaining STIG compliance. Therefore, our customers can focus on their core missions while maintaining the highest security standards. Our customers can use AWS EC2 Image Builder’s existing Linux hardening components, which now support AL2023 Category I, II, and III findings to automatically create STIG-compliant AL2023 EC2 images with minimal manual intervention. This automation significantly reduces the time and effort typically needed for security hardening implementations. The EC2 Image Builder Linux hardening component extends its proven capabilities to AL2023, providing the same streamlined security configuration process available for other Linux distributions. For more information, refer to the Image Builder documentation.

Automating the STIG for Existing Fleets via Systems Manager

For existing AL2023 EC2 instances, you can use AWS-managed SSM command documents to automate the implementation of the STIG configurations. . These command documents can be executed through the SSM console, API, or AWS Command Line Interface (AWS CLI). The key mechanism here is the AWS managed Systems Manager command document, which contains the pre-defined STIG configurations. By leveraging these command documents through Systems Manager execution capabilities, customers can systematically deploy and maintain AL2023 STIG configurations across their fleet of EC2 instances. This generates consistent security baselines that meet government and enterprise requirements. This solution is particularly effective for environments with existing AL2023 EC2 instances as it allows customers to implement STIG controls without rebuilding or redeploying instances. For more information about the command document, refer to Apply STIG settings with Systems Manager in the EC2 User Guide.

The AL2023 STIG represents the continued commitment of Amazon Linux to providing customers with the security tools and guidance they need to succeed in highly regulated environments. Amazon Linux, in collaboration with DISA is providing their customers with access to authoritative, government-validated security configurations that meet the most demanding compliance requirements.

Ready to implement AL2023 STIG in your environment? Explore our comprehensive documentation and begin streamlining your security compliance journey today. To learn more about STIG hardening for your EC2 instances, refer to STIG compliance for your EC2 instance and for STIG settings that are applied to EC2 Linux instances, refer to the STIG settings for EC2 Linux instances. To apply STIG settings to your AL 2023 EC2 instance, download the AL2023 DISA STIG.

New general-purpose Amazon EC2 M8i and M8i Flex instances are now available

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/new-general-purpose-amazon-ec2-m8i-and-m8i-flex-instances-are-now-available/

Today, we’re announcing the general availability of Amazon Elastic Compute Cloud (Amazon EC2) general-purpose M8i and M8i-Flex instances powered by custom Intel Xeon 6 processors available only on AWS with sustained all-core 3.9 GHz turbo frequency. These instances deliver the highest performance and fastest memory bandwidth among comparable Intel processors in the cloud. They also deliver up to 15 percent better price performance, up to 20 percent higher performance, and 2.5 times more memory bandwidth compared to previous generation M7i and M7i-Flex instances.

M8i and M8i-flex instances are ideal for running general purpose workloads such as general web application servers, virtual desktops, batch processing, microservices, databases, and enterprise applications. In terms of performance, these instances are specifically up to 60 percent faster for NGINX web applications, up to 30 percent faster for PostgreSQL database workloads, and up to 40 percent faster for AI deep learning recommendation models compared to M7i and M7i-Flex instances.

As like R8i and R8i-Flex instances, these instances use the new sixth generation AWS Nitro Cards, delivering up to two times more network and Amazon Elastic Block Storage (Amazon EBS) bandwidth compared to the previous generation instances. It greatly improves network throughput for workloads handling small packets such as web, application, and gaming servers. They also support bandwidth configuration with 25 percent allocation adjustments between network and Amazon EBS bandwidth, enabling better database performance, query processing, and logging speeds.

M8i instances
M8i instances provide up to 384 vCPUs and 1.5 TB memory including bare metal instances that provide dedicated access to the underlying physical hardware. These SAP-certified instances help you to run large application servers and databases, gaming servers, CPU-based inference, and video streaming that need the largest instance sizes or high CPU continuously.

Here are the specs for M8i instances:

Instance size vCPUs Memory (GiB) Network bandwidth (Gbps) EBS bandwidth (Gbps)
m8i.large 2 8 Up to 12.5 Up to 10
m8i.xlarge 4 16 Up to 12.5 Up to 10
m8i.2xlarge 8 32 Up to 15 Up to 10
m8i.4xlarge 16 64 Up to 15 Up to 10
m8i.8xlarge 32 128 15 10
m8i.12xlarge 48 192 22.5 15
m8i.16xlarge 64 256 30 20
m8i.24xlarge 96 384 40 30
m8i.32xlarge 128 512 50 40
m8i.48xlarge 192 768 75 60
m8i.96xlarge 384 1536 100 80
m8i.metal-48xl 192 768 75 60
m8i.metal-96xl 384 1536 100 80

M8i-Flex instances
M8i-Flex instances are a lower-cost variant of the M8i instances, with 5 percent better price performance at 5 percent lower prices. They’re designed for workloads that benefit from the latest generation performance but don’t fully utilize all compute resources. These instances can reach up to the full CPU performance 95 percent of the time.

Here are the specs for the M8i-Flex instances:

Instance size vCPUs Memory (GiB) Network bandwidth (Gbps) EBS bandwidth (Gbps)
m8i-flex.large 2 8 Up to 12.5 Up to 10
m8i-flex.xlarge 4 16 Up to 12.5 Up to 10
m8i-flex.2xlarge 8 32 Up to 15 Up to 10
m8i-flex.4xlarge 16 64 Up to 15 Up to 10
m8i-flex.8xlarge 32 128 Up to 15 Up to 10
m8i-flex.12xlarge 48 192 Up to 22.5 Up to 15
m8i-flex.16xlarge 64 256 Up to 30 Up to 20

If you’re currently using earlier generations of general-purpose instances, you can adopt M8i-Flex instances without having to make changes to your application or your workload.

Now available
Amazon EC2 M8i and M8i-Flex instances are available today in the US East (N. Virginia), US East (Ohio), US West (Oregon), and Europe (Spain) AWS Regions. M8i and M8i-Flex instances can be purchased as On-Demand, Savings Plan, and Spot instances. M8i instances are also available in Dedicated Instances and Dedicated Hosts. To learn more, visit the Amazon EC2 Pricing page.

Give M8i and M8i-Flex instances a try in the Amazon EC2 console. To learn more, visit the Amazon EC2 M8i instances page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

Channy

Best performance and fastest memory with the new Amazon EC2 R8i and R8i-flex instances

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/best-performance-and-fastest-memory-with-the-new-amazon-ec2-r8i-and-r8i-flex-instances/

Today, we’re announcing general availability of the new eighth generation, memory optimized Amazon Elastic Compute Cloud (Amazon EC2) R8i and R8i-flex instances powered by custom Intel Xeon 6 processors, available only on AWS. They deliver the highest performance and fastest memory bandwidth among comparable Intel processors in the cloud. These instances deliver up to 15 percent better price performance, 20 percent higher performance, and 2.5 times more memory throughput compared to previous generation instances.

With these improvements, R8i and R8i-flex instances are ideal for a variety of memory intensive workloads such as SQL and NoSQL databases, distributed web scale in-memory caches (Memcached and Redis), in-memory databases such as SAP HANA, and real-time big data analytics (Apache Hadoop and Apache Spark clusters). For a majority of the workloads that don’t fully utilize the compute resources, the R8i-flex instances are a great first choice to achieve an additional 5 percent better price performance and 5 percent lower prices.

Improvements made to both instances compared to their predecessors
In terms of performance, R8i and R8i-flex instances offer 20 percent better performance than R7i instances, with even higher gains for specific workloads. These instances are up to 30 percent faster for PostgreSQL databases, up to 60 percent faster for NGINX web applications, and up to 40 percent faster for AI deep learning recommendation models compared to previous generation R7i instances, with sustained all-core turbo frequency now reaching 3.9 GHz (compared to 3.2 GHz in the previous generation). They also feature a 4.6x larger L3 cache and significantly better memory throughput, offering 2.5 times higher memory bandwidth than the seventh generation. With this higher performance across all the vectors, you can run a greater number of workloads while keeping costs down.

R8i instances now scale up to 96xlarge with up to 384 vCPUs and 3TB memory (versus 48xlarge sizes in the seventh generation), helping you to scale up database applications. R8i instances are SAP certified to deliver 142,100 aSAPS, which is highest among all comparable machines in on premises and cloud environments, delivering exceptional performance for your mission-critical SAP workloads. R8i-flex instances offer the most common sizes, from large to 16xlarge, and are a great first choice for applications that don’t fully utilize all compute resources. Both R8i and R8i-flex instances use the latest sixth generation AWS Nitro Cards, delivering up to two times more network and Amazon Elastic Block Storage (Amazon EBS) bandwidth compared to the previous generation, which greatly improves network throughput for workloads handling small packets, such as web, application, and gaming servers.

R8i and R8i-flex instances also support bandwidth configuration with 25 percent allocation adjustments between network and Amazon EBS bandwidth, enabling better database performance, query processing, and logging speeds. Additional enhancements include FP16 datatype support for Intel AMX to support workloads such as deep learning training and inference and other artificial intelligence and machine learning (AI/ML) applications.

The specs for the R8i instances are as follows.

Instance size
vCPUs
Memory (GiB)
Network bandwidth (Gbps)
EBS bandwidth (Gbps)
r8i.large 2 16 Up to 12.5 Up to 10
r8i.xlarge 4 32 Up to 12.5 Up to 10
r8i.2xlarge 8 64 Up to 15 Up to 10
r8i.4xlarge 16 128 Up to 15 Up to 10
r8i.8xlarge 32 256 15 10
r8i.12xlarge 48 384 22.5 15
r8i.16xlarge 64 512 30 20
r8i.24xlarge 96 768 40 30
r8i.32xlarge 128 1024 50 40
r8i.48xlarge 192 1536 75 60
r8i.96xlarge 384 3072 100 80
r8i.metal-48xl 192 1536 75 60
r8i.metal-96xl 384 3072 100 80

The specs for the R8i-flex instances are as follows.

Instance size
vCPUs
Memory (GiB)
Network bandwidth (Gbps)
EBS bandwidth (Gbps)
r8i-flex.large 2 16 Up to 12.5 Up to 10
r8i-flex.xlarge 4 32 Up to 12.5 Up to 10
r8i-flex.2xlarge 8 64 Up to 15 Up to 10
r8i-flex.4xlarge 16 128 Up to 15 Up to 10
r8i-flex.8xlarge 32 256 Up to 15 Up to 10
r8i-flex.12xlarge 48 384 Up to 22.5 Up to 15
r8i-flex.16xlarge 64 512 Up to 30 Up to 20

When to use the R8i-flex instances
As stated earlier, R8i-flex instances are more affordable versions of the R8i instances, offering up to 5 percent better price performance at 5 percent lower prices. They’re designed for workloads that benefit from the latest generation performance but don’t fully use all compute resources. These instances can reach up to the full CPU performance 95 percent of the time and work well for in-memory databases, distributed web scale cache stores, mid-size in-memory analytics, real-time big data analytics, and other enterprise applications. R8i instances are recommended for more demanding workloads that need sustained high CPU, network, or EBS performance such as analytics, databases, enterprise applications, and web scale in-memory caches.

Available now
R8i and R8i-flex instances are available today in the US East (N. Virginia), US East (Ohio), US West (Oregon), and Europe (Spain) AWS Regions. As usual with Amazon EC2, you pay only for what you use. For more information, refer to Amazon EC2 Pricing. Check out the full collection of memory optimized instances to help you start migrating your applications.

To learn more, visit our Amazon EC2 R8i instances page and Amazon EC2 R8i-flex instances page. Send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

– Veliswa

AWS Weekly Roundup: Kiro, AWS Lambda remote debugging, Amazon ECS blue/green deployments, Amazon Bedrock AgentCore, and more (July 21, 2025)

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-kiro-aws-lambda-remote-debugging-amazon-ecs-blue-green-deployments-amazon-bedrock-agentcore-and-more-july-21-2025/

I’m writing this as I depart from Ho Chi Minh City back to Singapore. Just realized what a week it’s been, so let me rewind a bit. This week, I tried my first Corne keyboard, wrapped up rehearsals for AWS Summit Jakarta with speakers who are absolutely raising the bar, and visited Vietnam to participate as a technical keynote speaker in AWS Community Day Vietnam, an energetic gathering of hundreds of cloud practitioners and AWS enthusiasts who shared knowledge through multiple technical tracks and networking sessions.

What I presented was a keynote titled “Reinvent perspective as modern developers”, featuring serverless, containers, and how we can cut the learning curves and be more productive with Amazon Q Developer and Kiro. I got a chance to discuss with a couple of AWS Community Builders and community developers, who shared how Amazon Q Developer actually addressed their challenges on building applications, with several highlighting significant productivity improvements and smoother learning curves in their cloud development journeys.

As I head back to Singapore, I’m carrying with me not just memories of delicious cà phê sữa đá (iced milk coffee), but also fresh perspectives and inspirations from this vibrant community of cloud innovators.

Introducing Kiro
One of the highlights from last week was definitely Kiro, an AI IDE that helps you deliver from concept to production through a simplified developer experience for working with AI agents. Kiro goes beyond “vibe coding” with features like specs and hooks that help get prototypes into production systems with proper planning and clarity.

Join the waitlist to get notified when it becomes available.

Last week’s AWS Launches
In other news, last week we had AWS Summit in New York, where we released several services. Here are some launches that caught my attention:

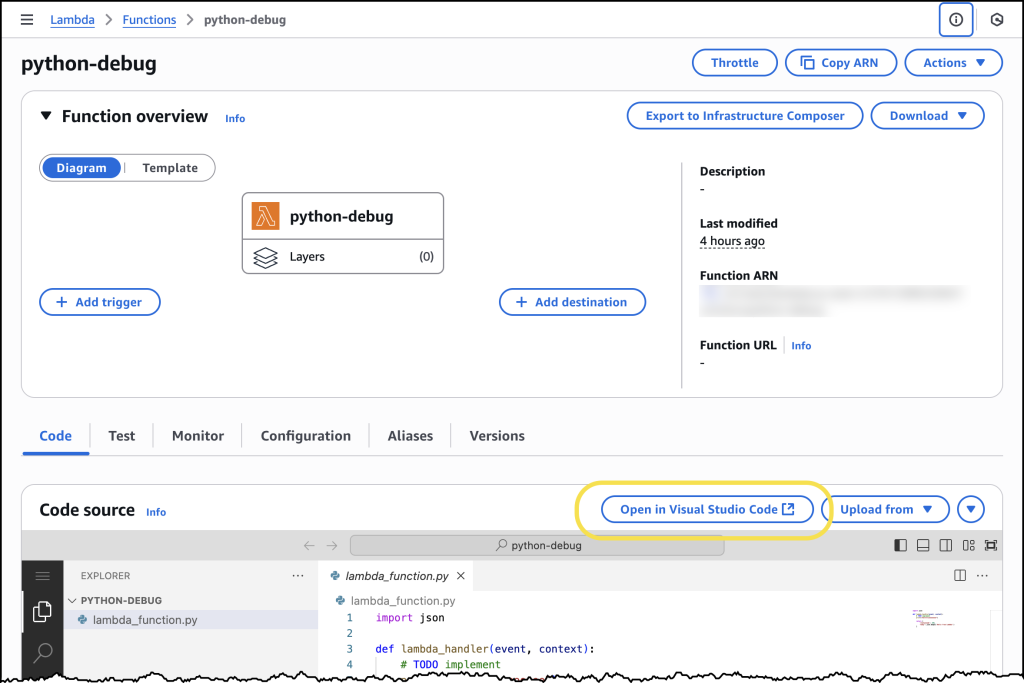
Console to IDE Integration

ECS Blue-Green Deployments

AWS Free Tier Enhanced Benefits

  • Monitor and debug event-driven applications with new Amazon EventBridge logging — Amazon EventBridge now provides enhanced logging capabilities that offer comprehensive event lifecycle tracking with detailed information about successes, failures, and status codes. This new observability feature addresses microservices and event-driven architecture monitoring challenges by providing visibility into the complete event journey.

EventBridge Enhanced Logging

S3 Vectors Overview

  • Amazon EKS enables ultra-scale AI/ML workloads with support for 100k nodes per cluster — Amazon EKS now supports up to 100,000 worker nodes in a single cluster, enabling customers to scale up to 1.6 million AWS Trainium accelerators or 800K NVIDIA GPUs. This industry-leading scale empowers customers to train trillion-parameter models and advance AGI development while maintaining Kubernetes conformance and familiar developer experience.

EKS Ultra-Scale Performance Improvements

From AWS Builder Center
In case you missed it, we just launched AWS Builder Center and integrated community.aws. Here are my top picks from the posts:

Upcoming AWS events
Check your calendars and sign up for upcoming AWS and AWS Community events:

  • AWS re:Invent – Register now to get a head start on choosing your best learning path, booking travel and accommodations, and bringing your team to learn, connect, and have fun. If you’re an early-career professional, you can apply to the All Builders Welcome Grant program, which is designed to remove financial barriers and create diverse pathways into cloud technology.
  • AWS Builders Online Series – If you’re based in one of the Asia Pacific time zones, join and learn fundamental AWS concepts, architectural best practices, and hands-on demonstrations to help you build, migrate, and deploy your workloads on AWS.
  • AWS Summits — Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Taipei (July 29), Mexico City (August 6), and Jakarta (June 26–27).
  • AWS Community Days — Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Singapore (August 2), Australia (August 15), Adria (September 5), Baltic (September 10), and Aotearoa (September 18).

You can browse all upcoming AWS led in-person and virtual developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

Donnie

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!


Join Builder ID: Get started with your AWS Builder journey at builder.aws.com

Accelerate safe software releases with new built-in blue/green deployments in Amazon ECS

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/accelerate-safe-software-releases-with-new-built-in-blue-green-deployments-in-amazon-ecs/

While containers have revolutionized how development teams package and deploy applications, these teams have had to carefully monitor releases and build custom tooling to mitigate deployment risks, which slows down shipping velocity. At scale, development teams spend valuable cycles building and maintaining undifferentiated deployment tools instead of innovating for their business.

Starting today, you can use the built-in blue/green deployment capability in Amazon Elastic Container Service (Amazon ECS) to make your application deployments safer and more consistent. This new capability eliminates the need to build custom deployment tooling while giving you the confidence to ship software updates more frequently with rollback capability.

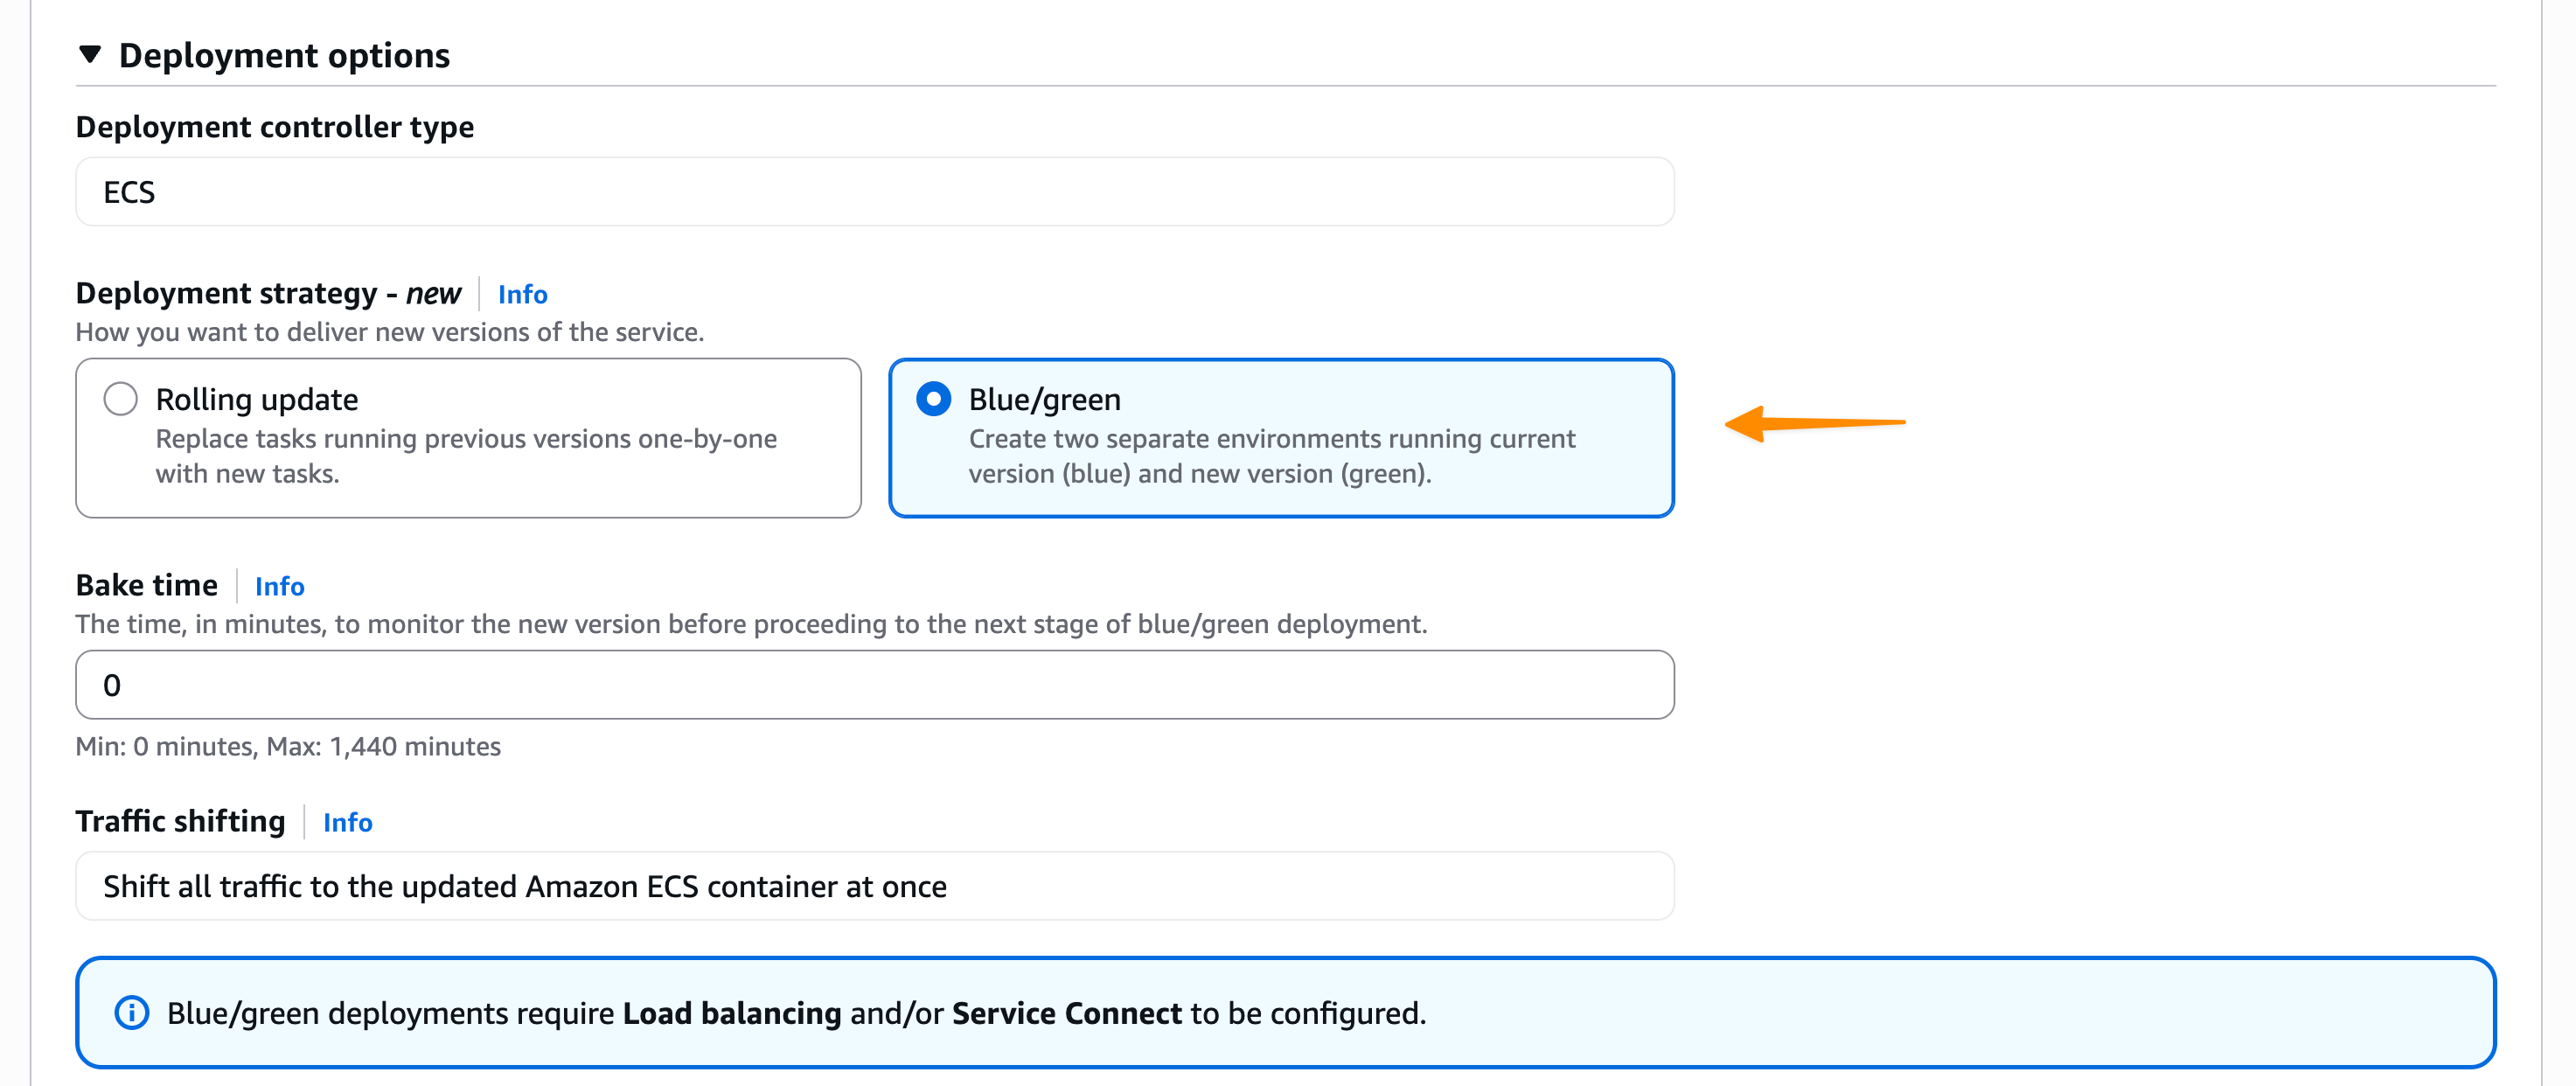
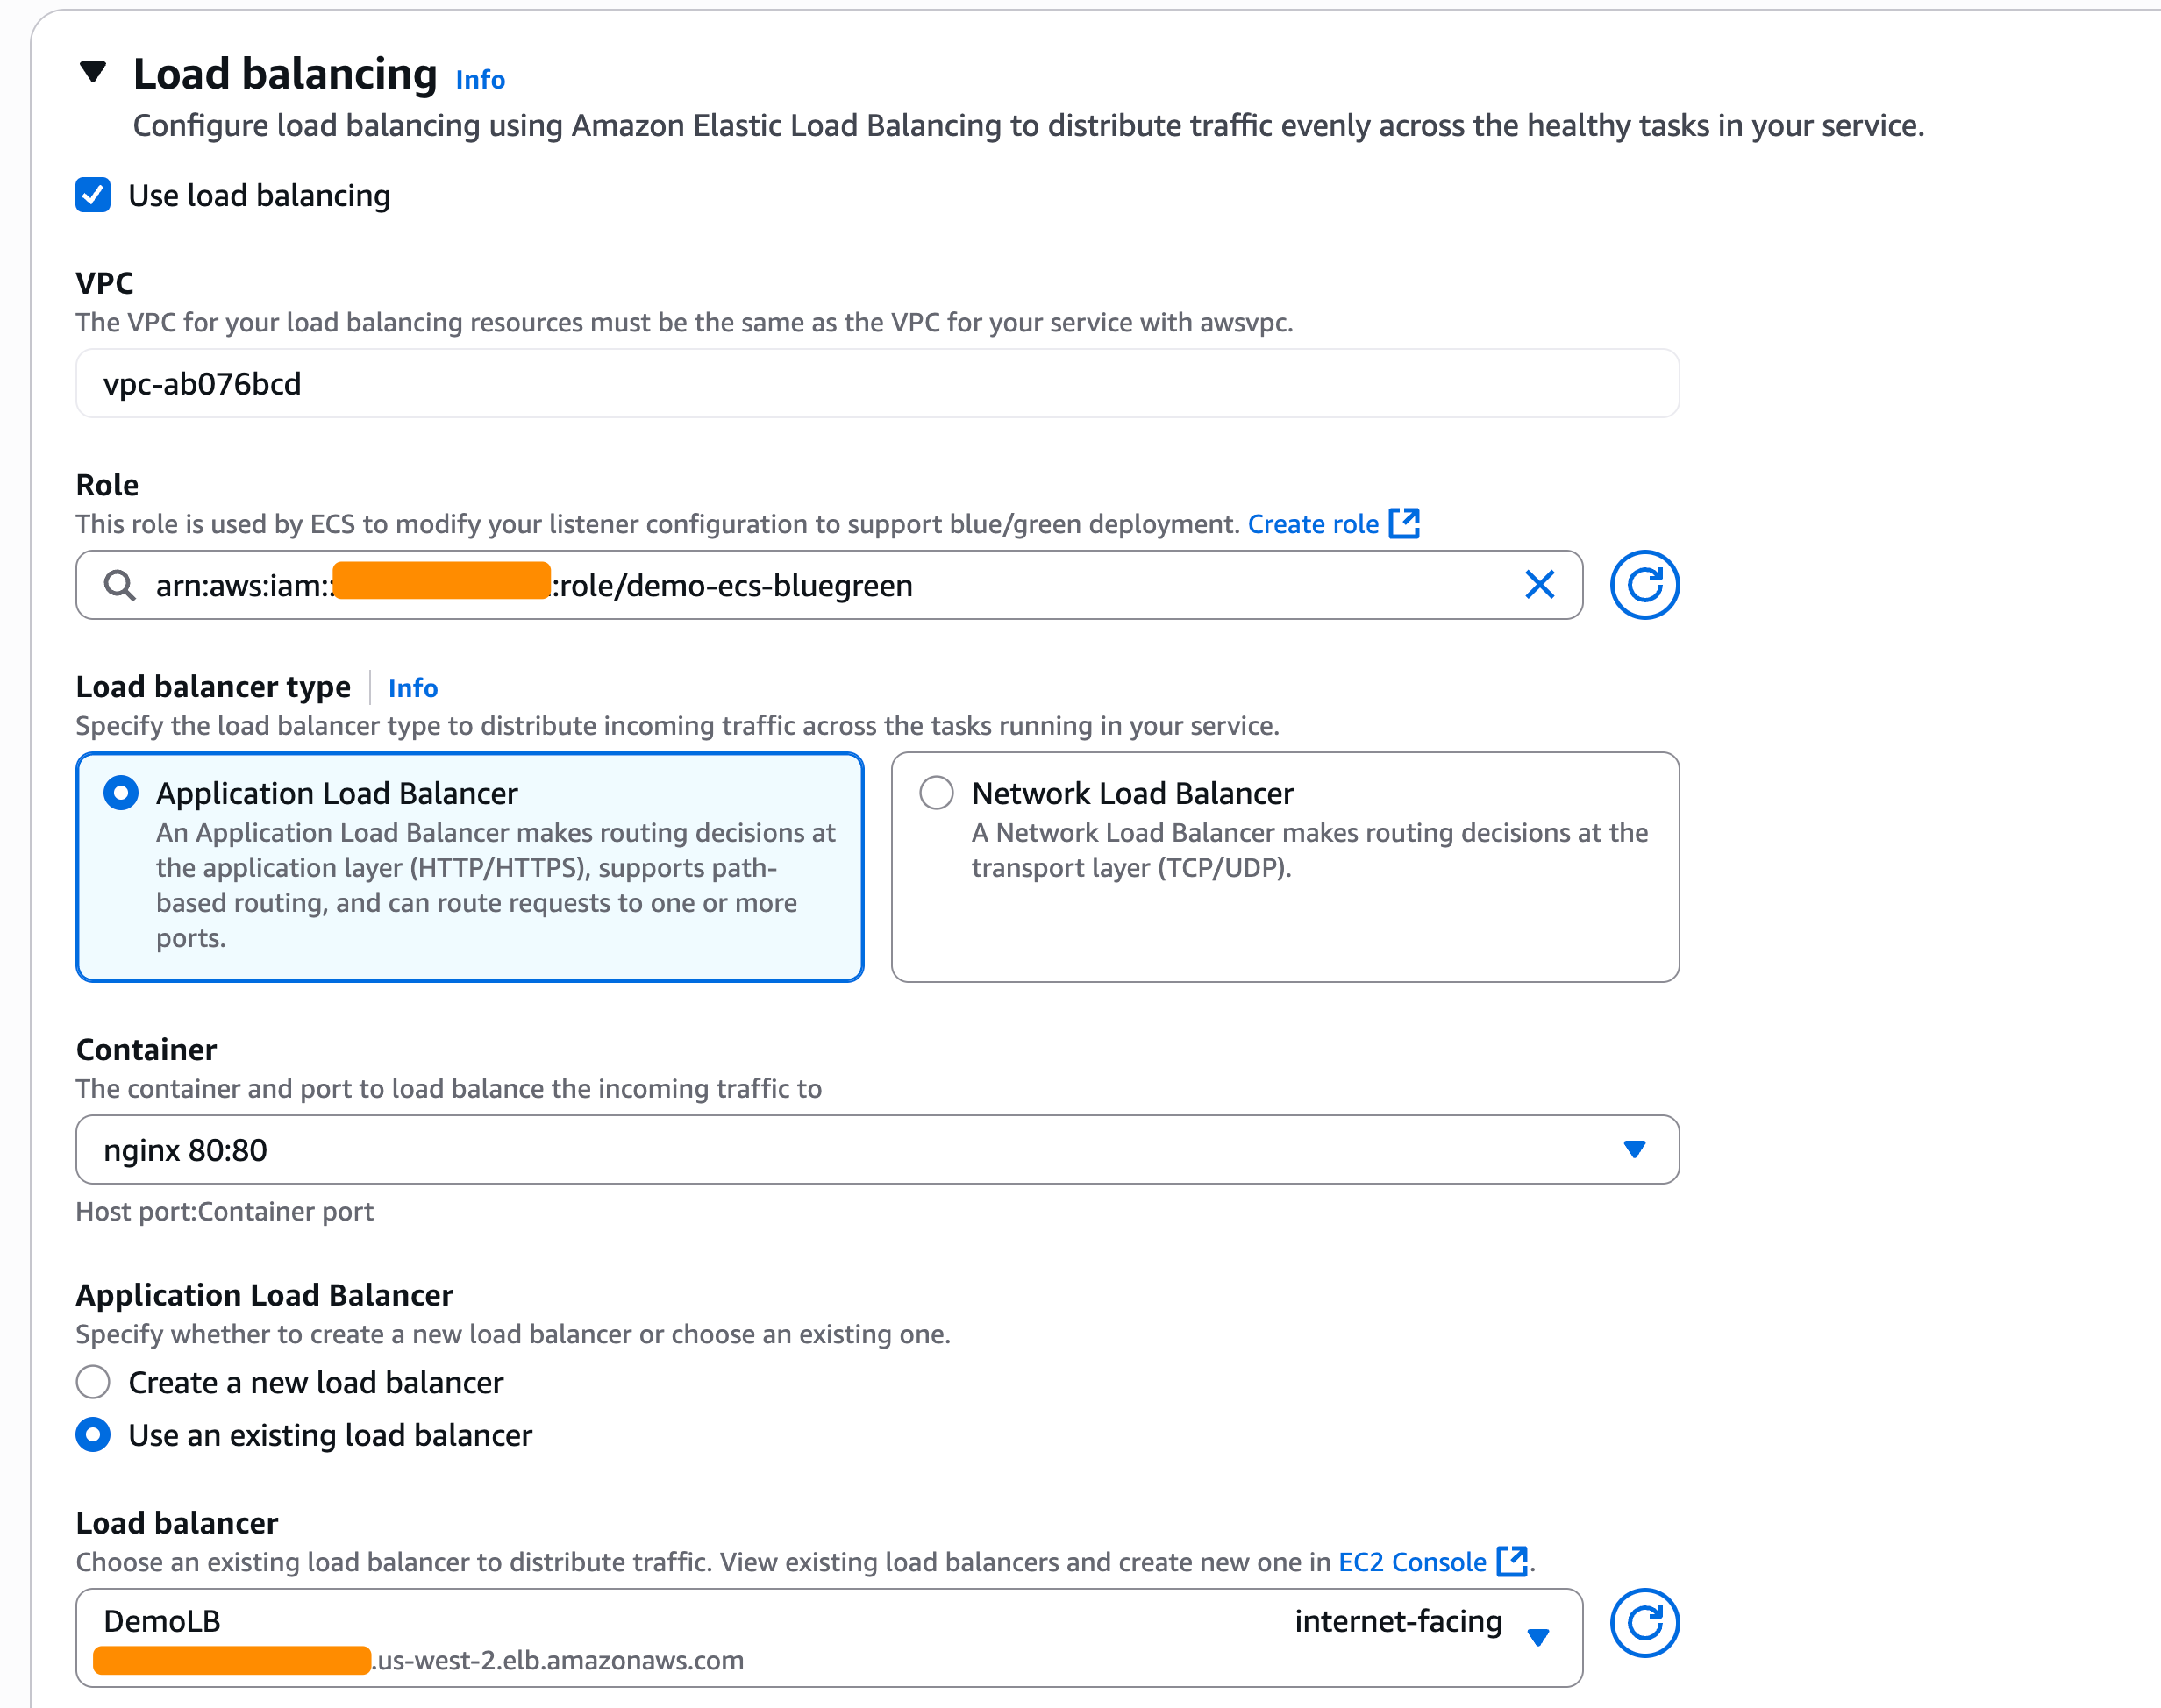
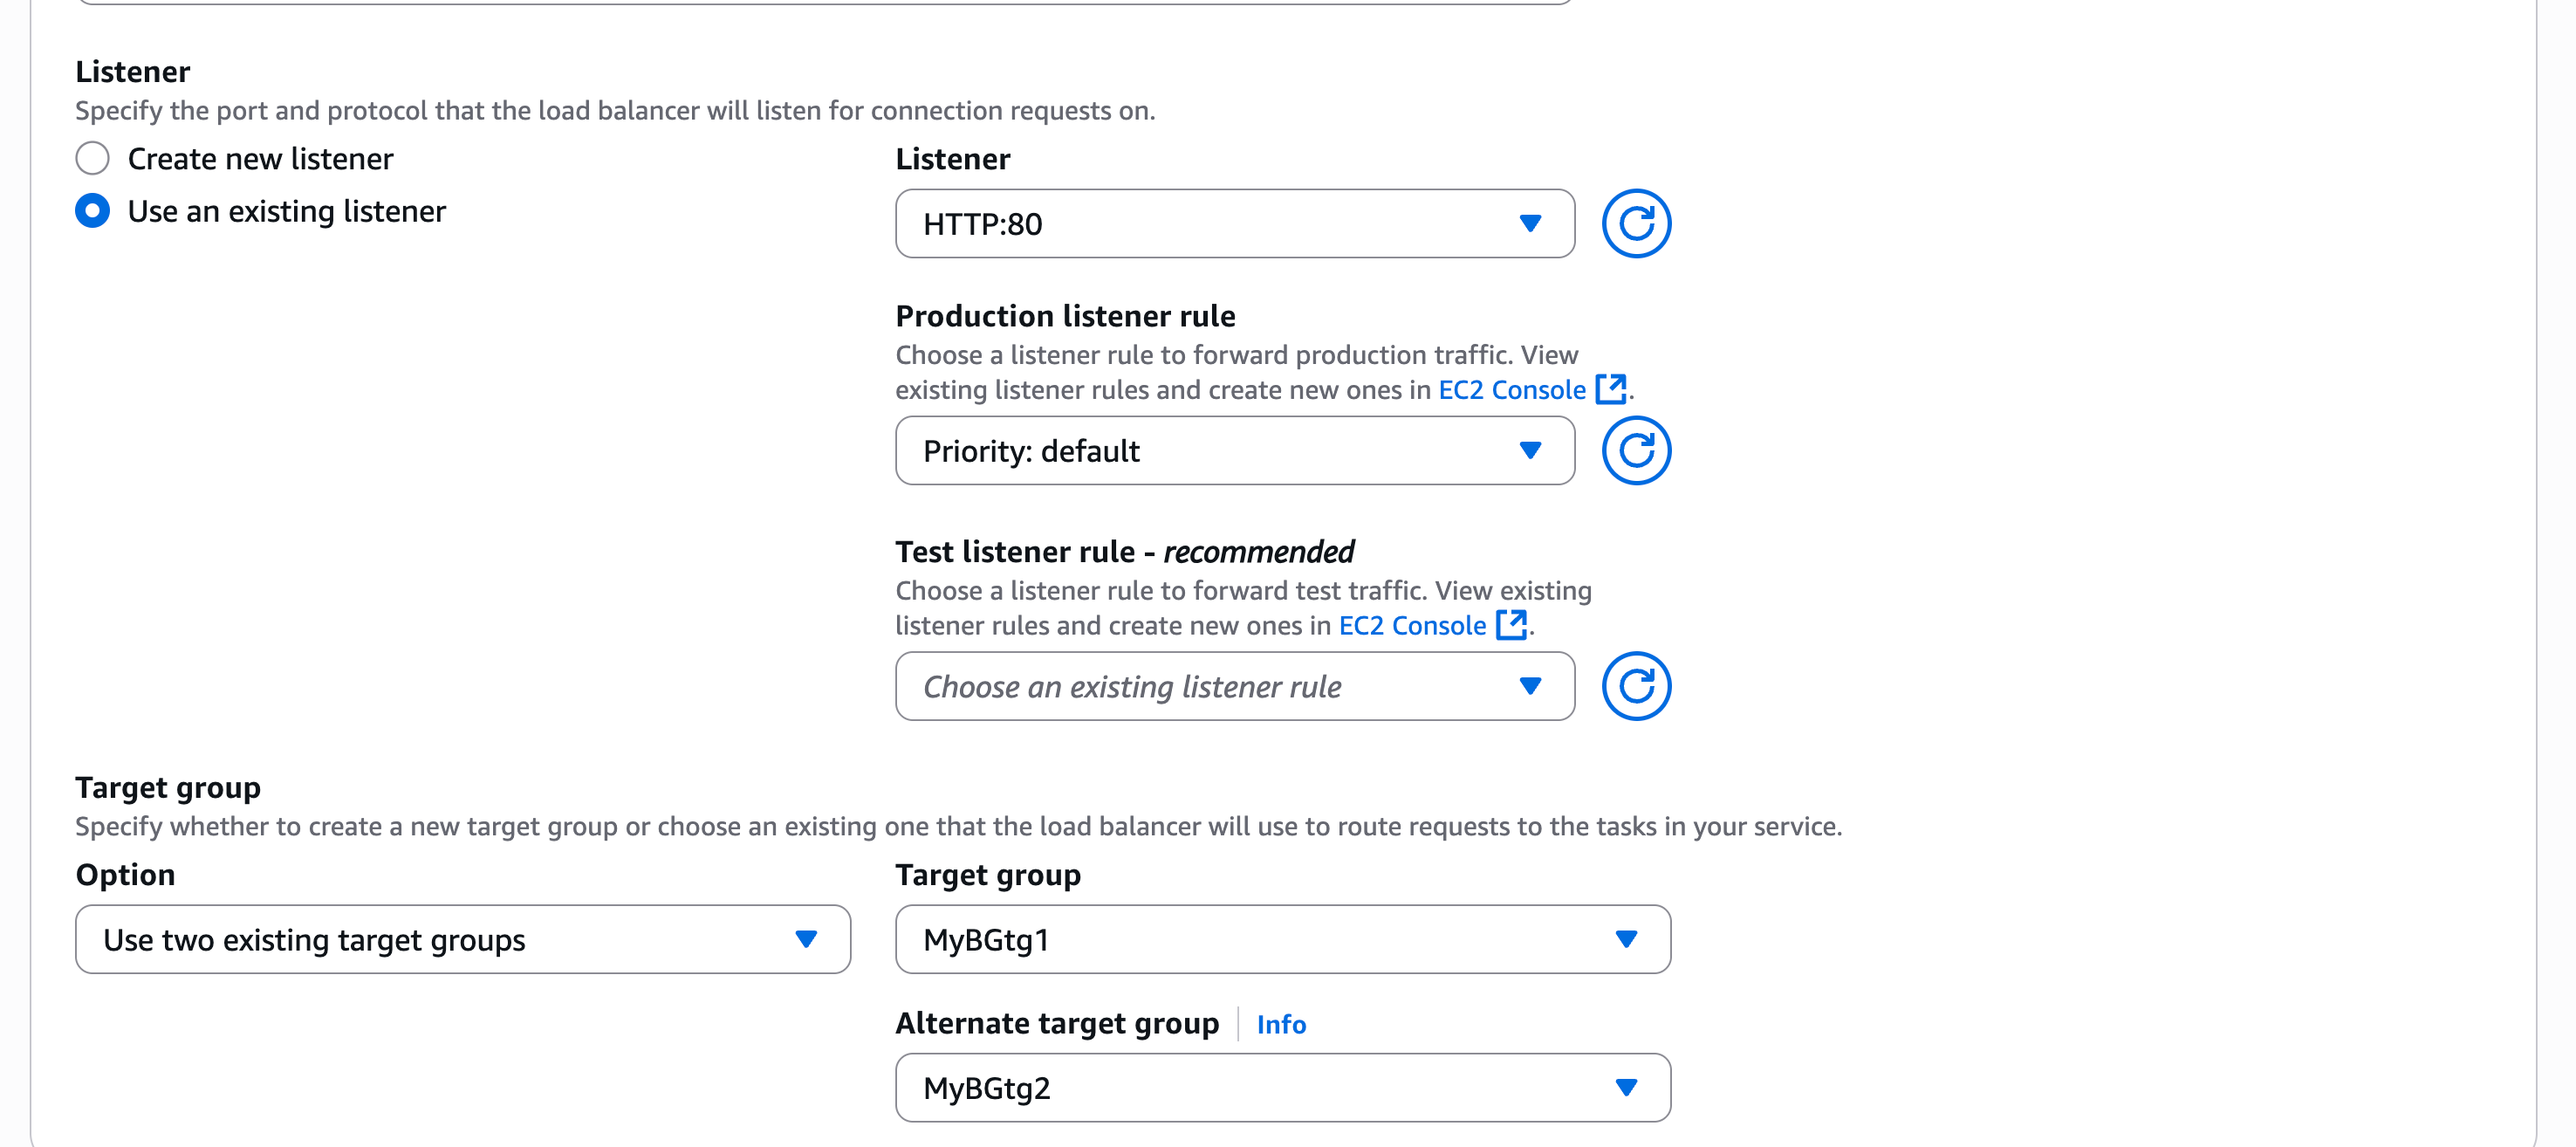
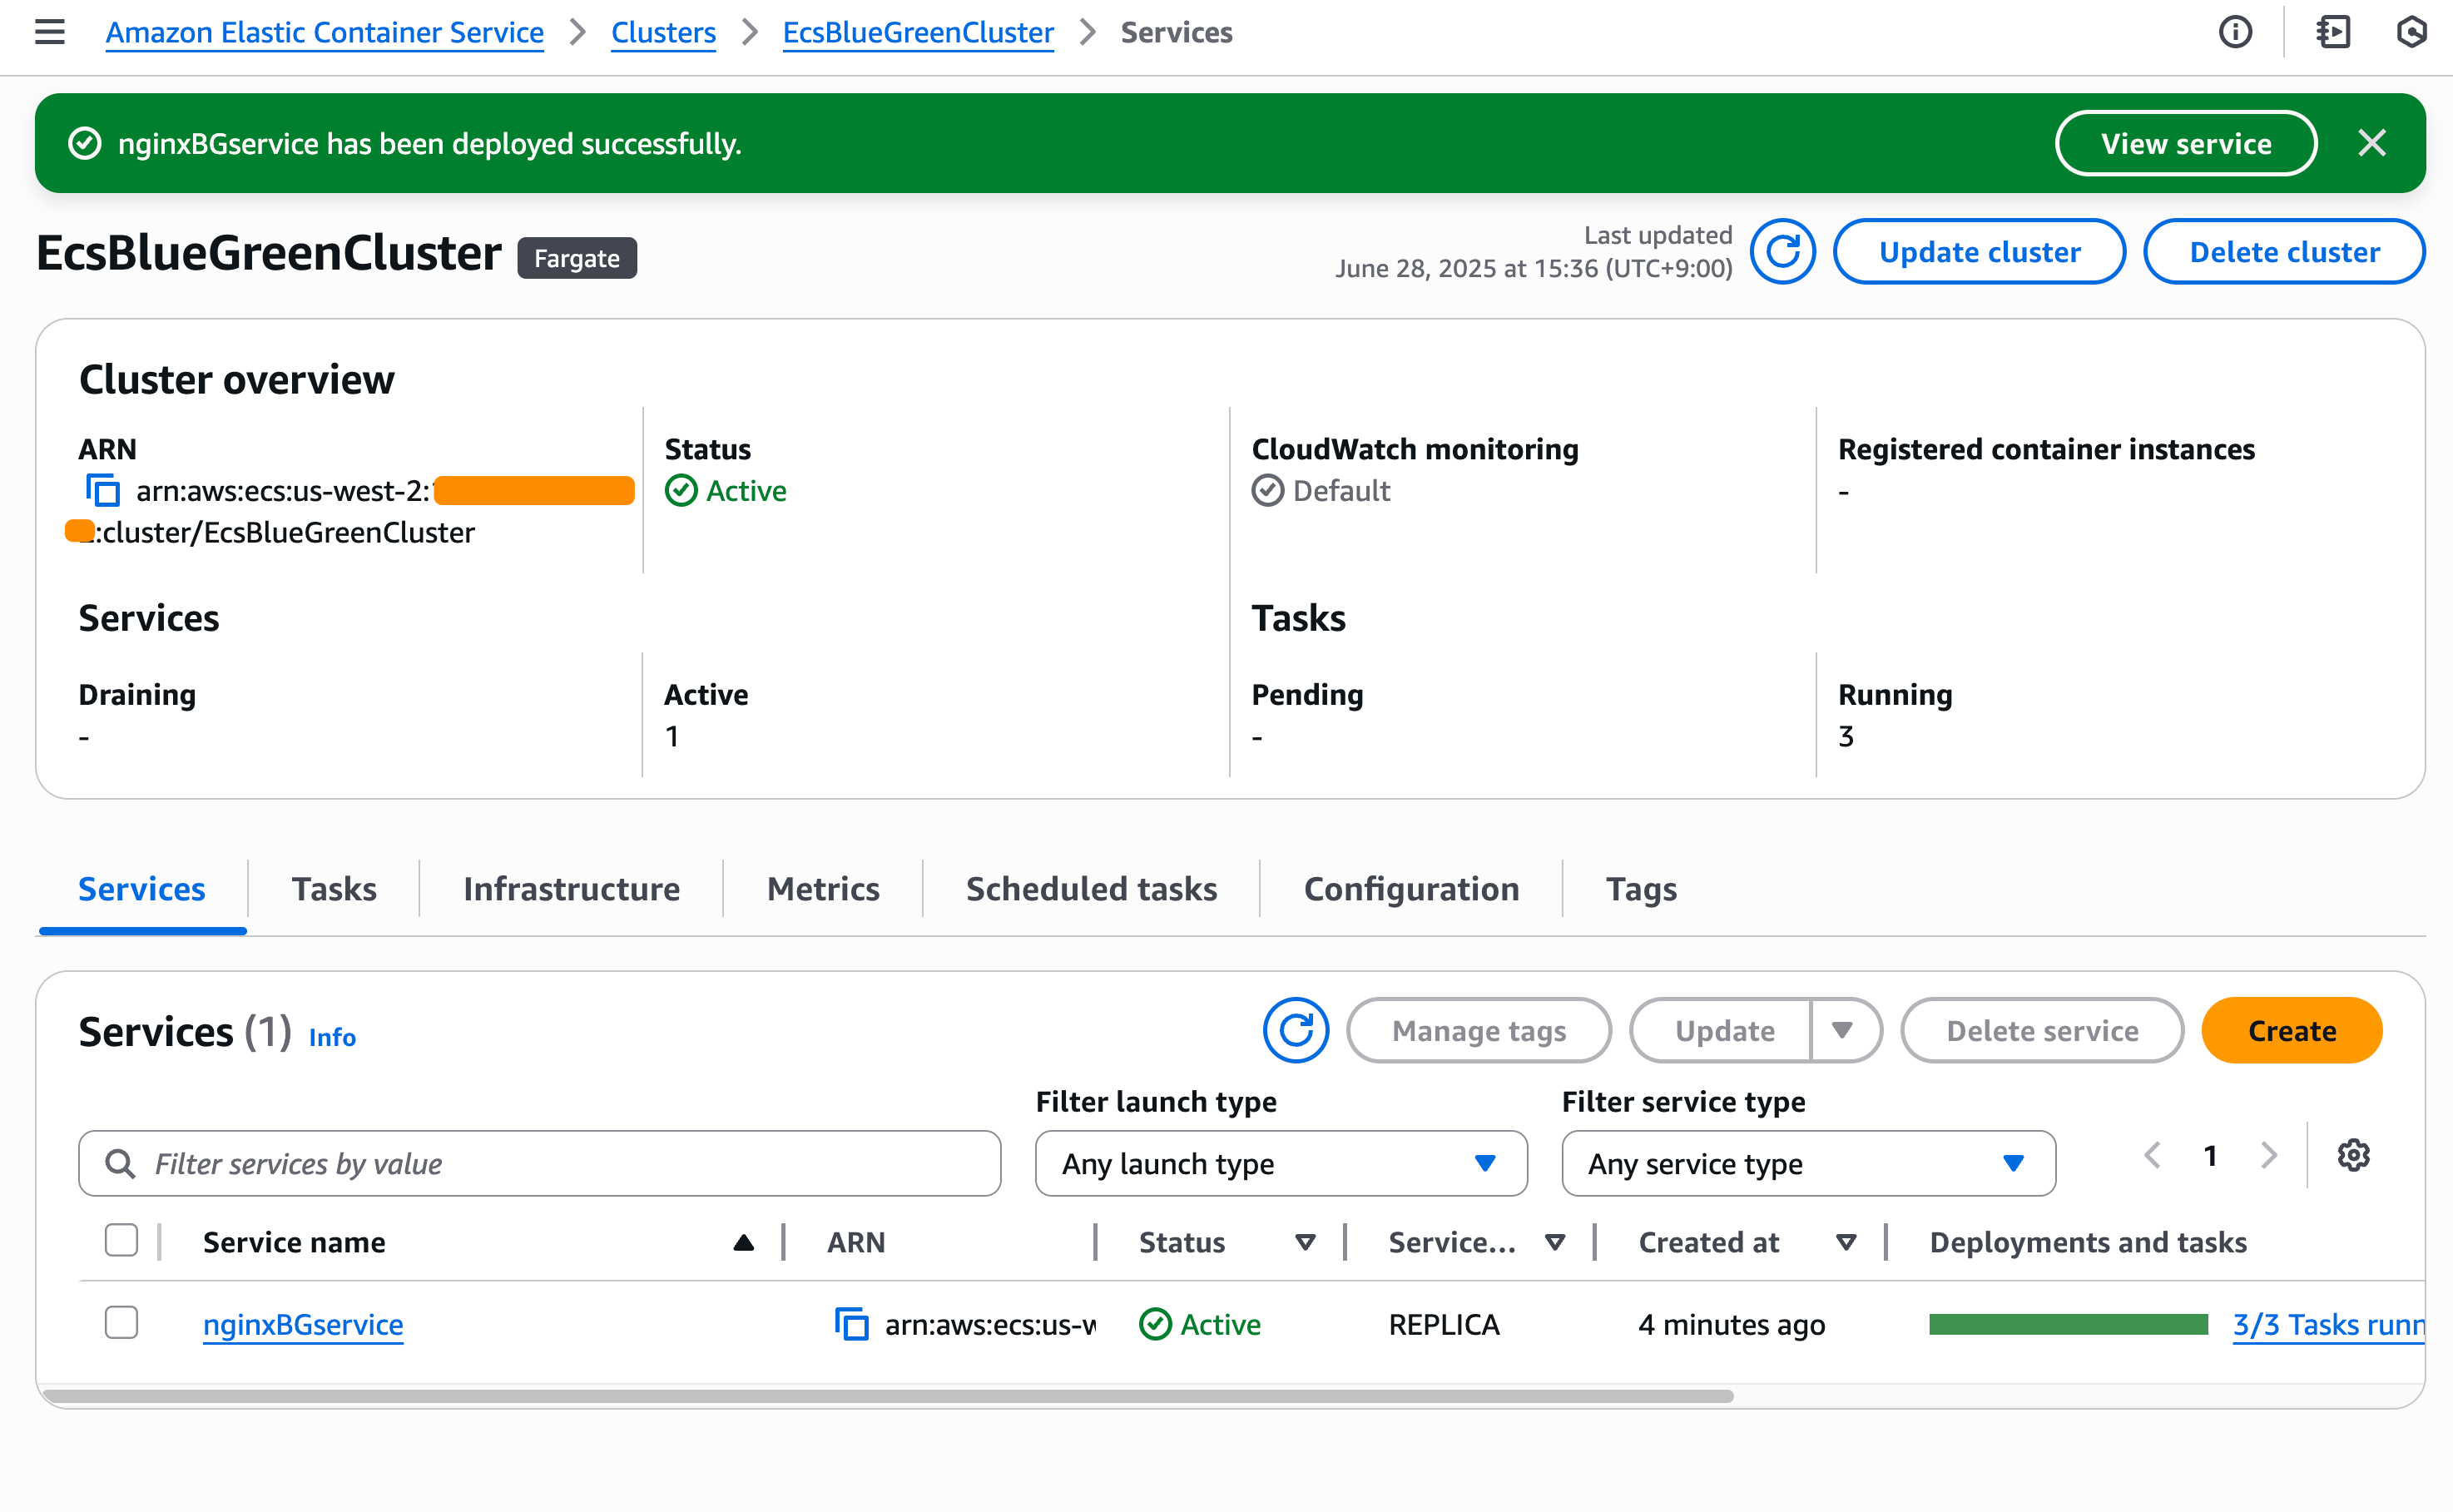
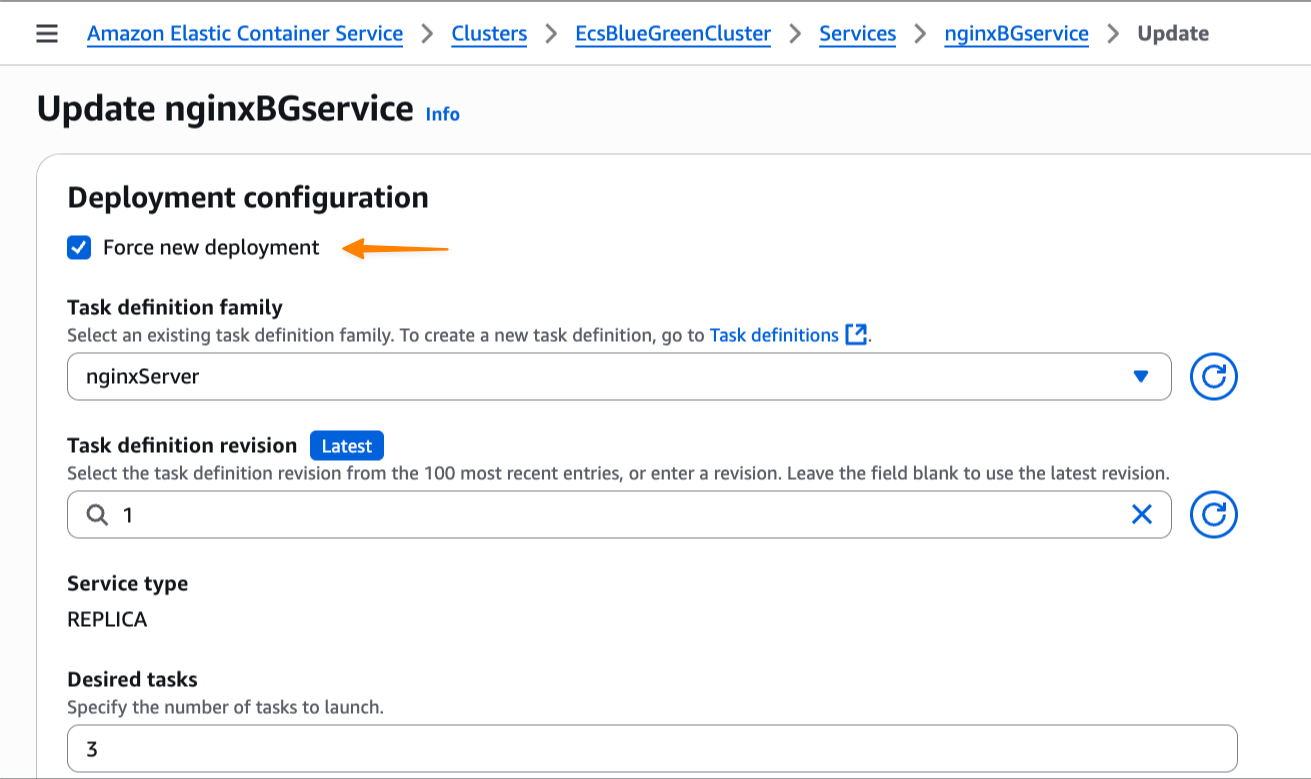
Here’s how you can enable the built-in blue/green deployment capability in the Amazon ECS console.

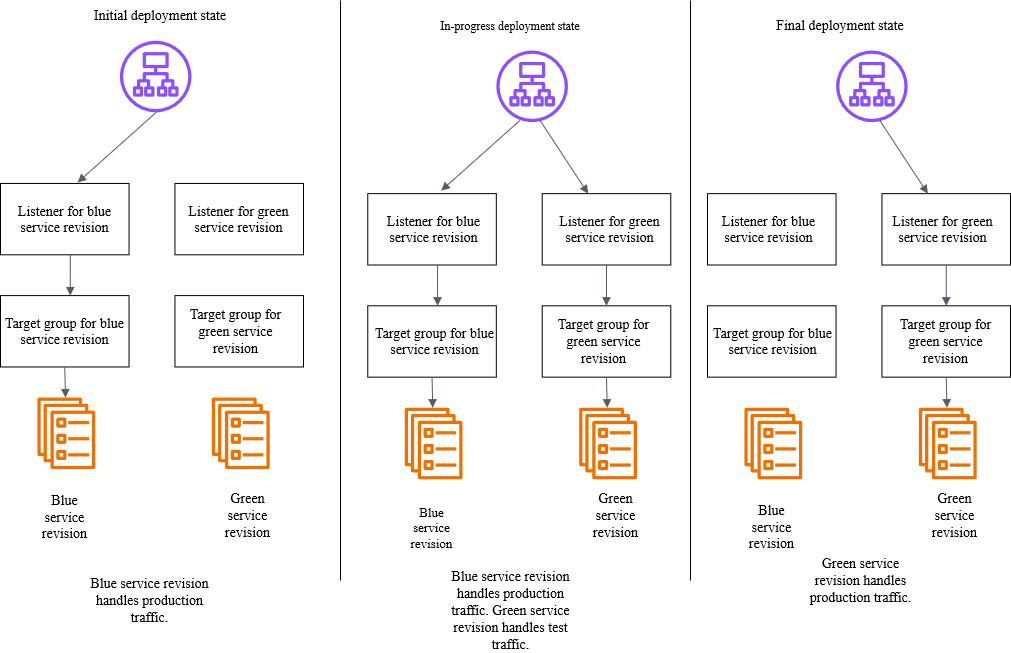
You create a new “green” application environment while your existing “blue” environment continues to serve live traffic. After monitoring and testing the green environment thoroughly, you route the live traffic from blue to green. With this capability, Amazon ECS now provides built-in functionality that makes containerized application deployments safer and more reliable.

Below is a diagram illustrating how blue/green deployment works by shifting application traffic from the blue environment to the green environment. You can learn more at the Amazon ECS blue/green service deployments workflow page.

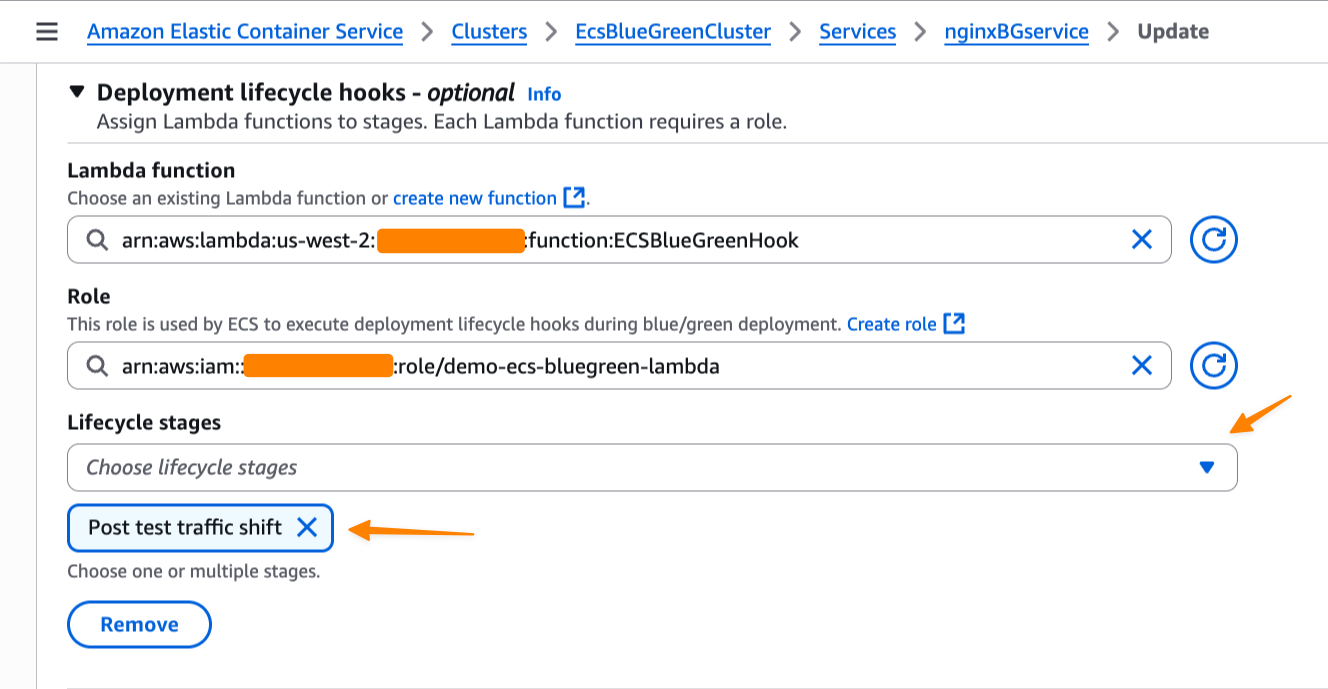
Amazon ECS orchestrates this entire workflow while providing event hooks to validate new versions using synthetic traffic before routing production traffic. You can validate new software versions in production environments before exposing them to end users and roll back near-instantaneously if issues arise. Because this functionality is built directly into Amazon ECS, you can add these safeguards by simply updating your configuration without building any custom tooling.

Getting started
Let me walk you through a demonstration that showcases how to configure and use blue/green deployments for an ECS service. Before that, there are a few setup steps that I need to complete, including configuring AWS Identity and Access Management (IAM) roles, which you can find on the Required resources for Amazon ECS blue/green deployments Documentation page.

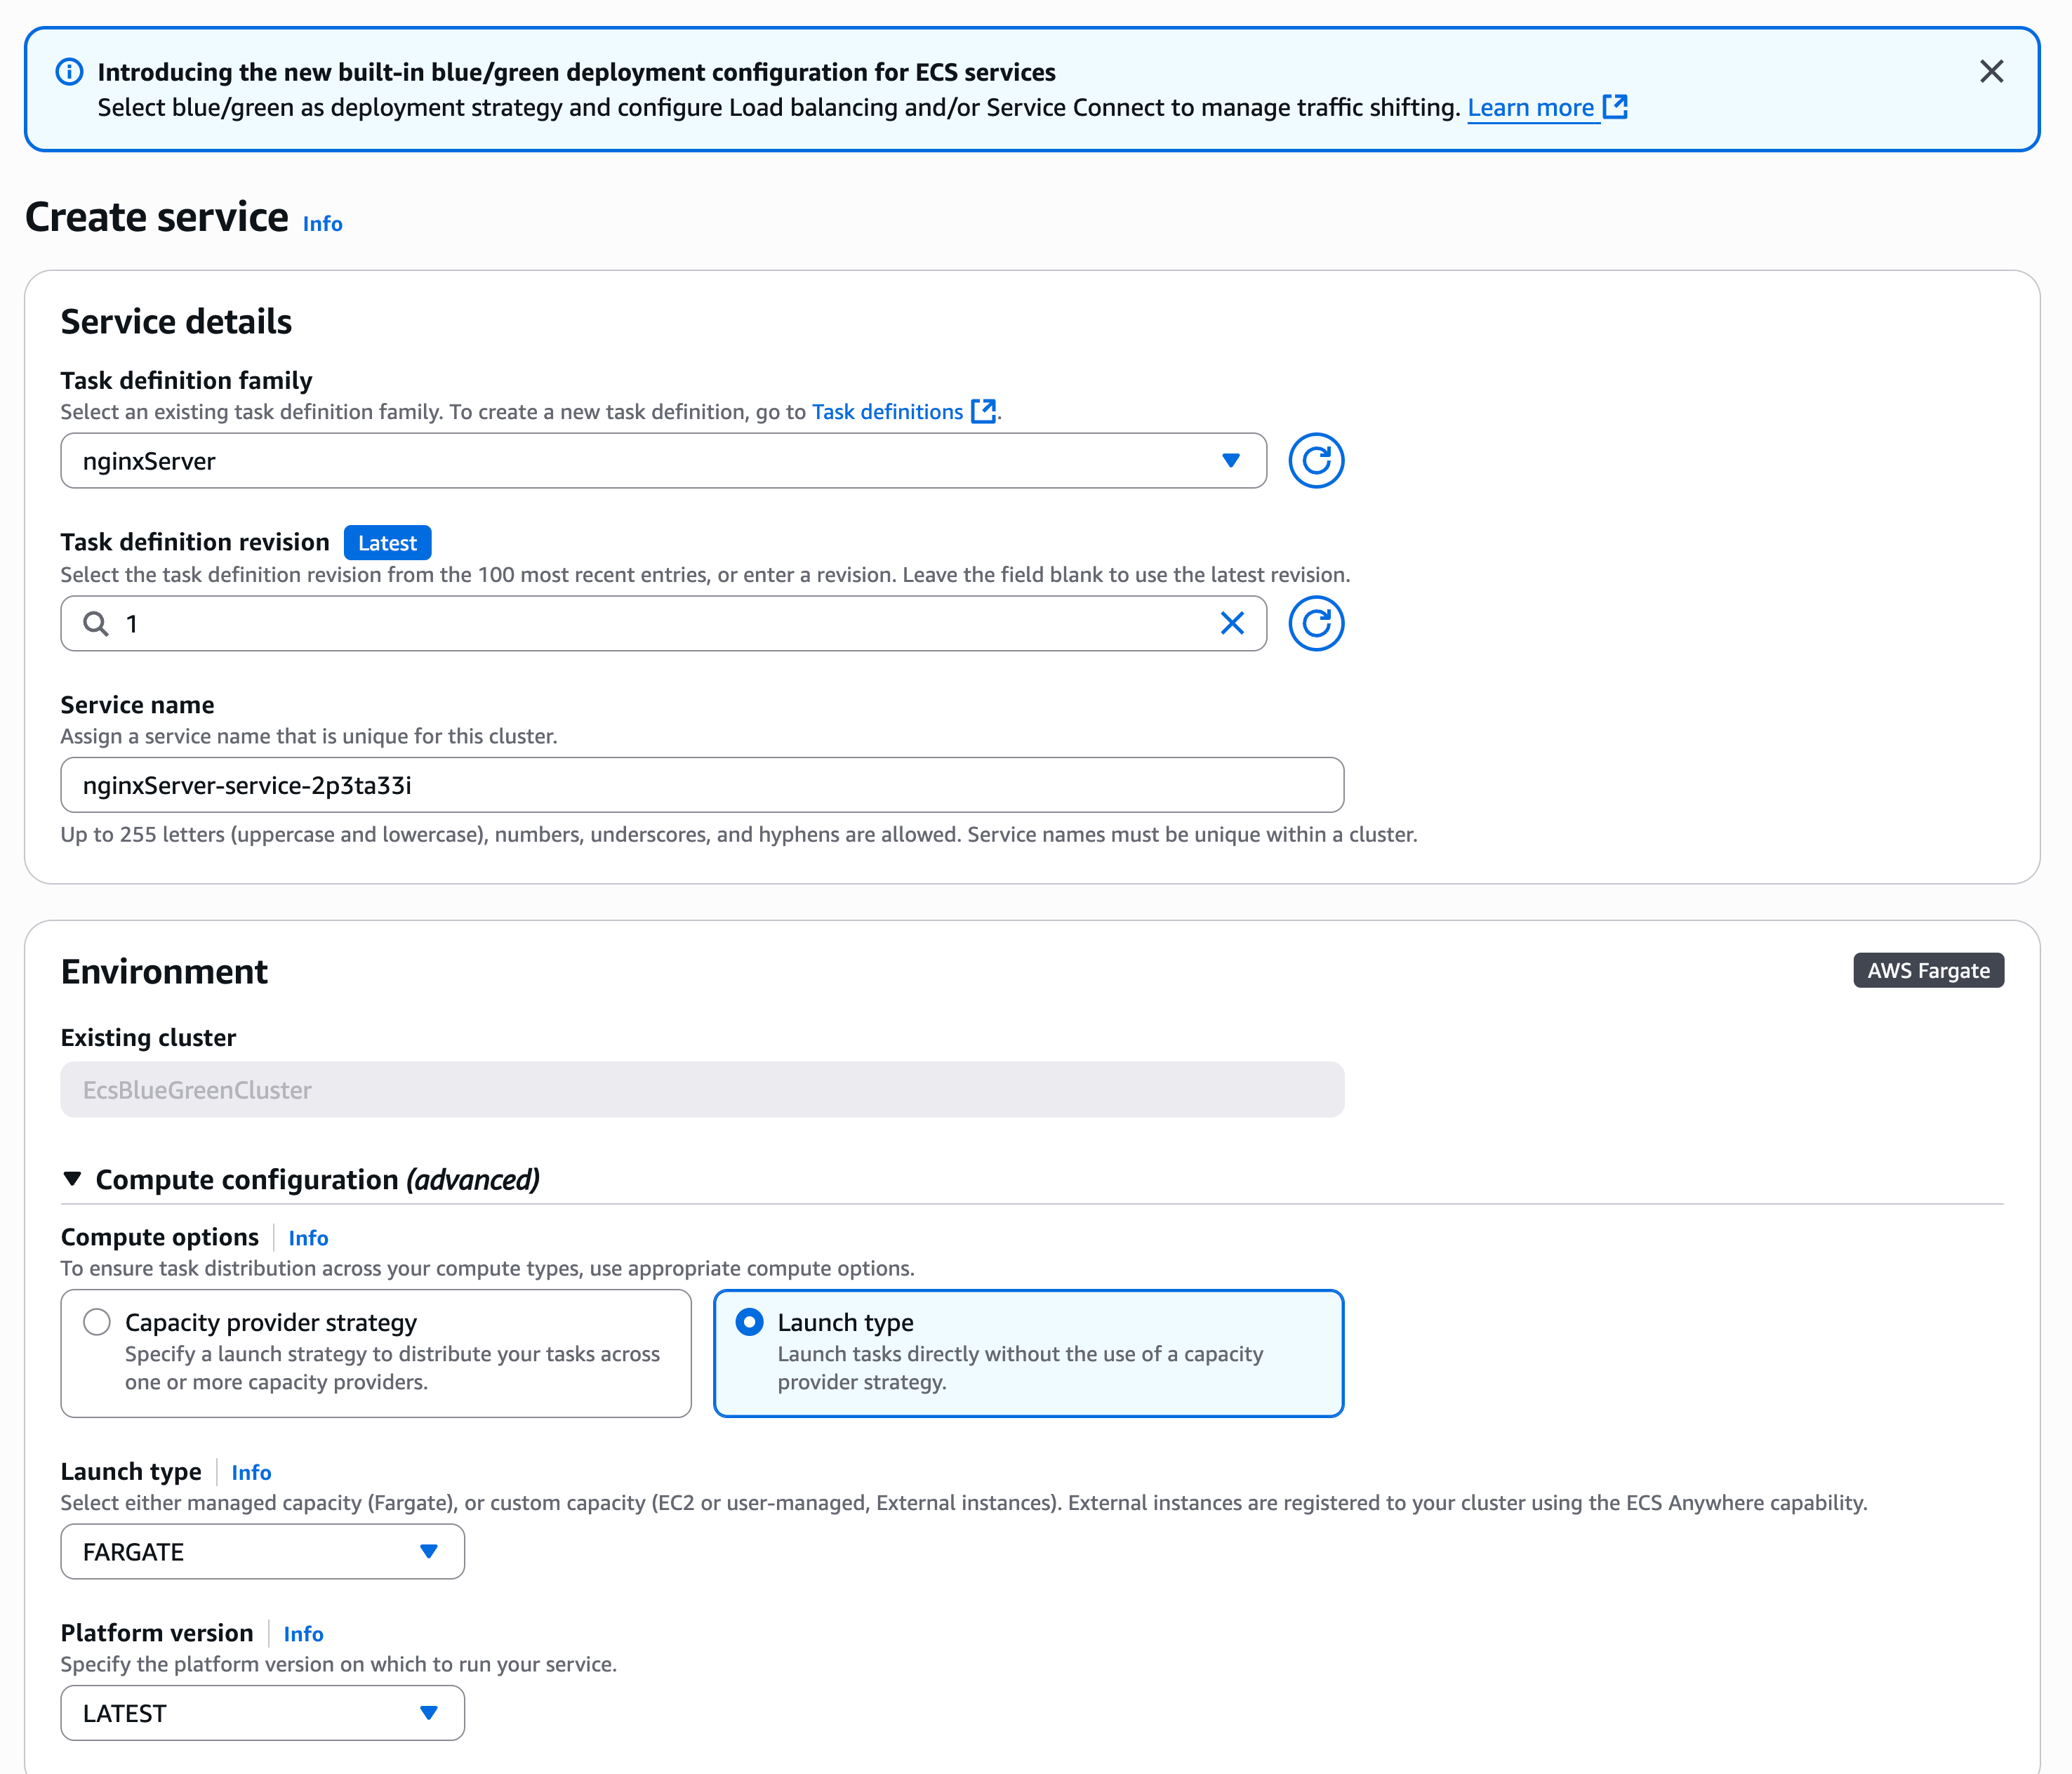
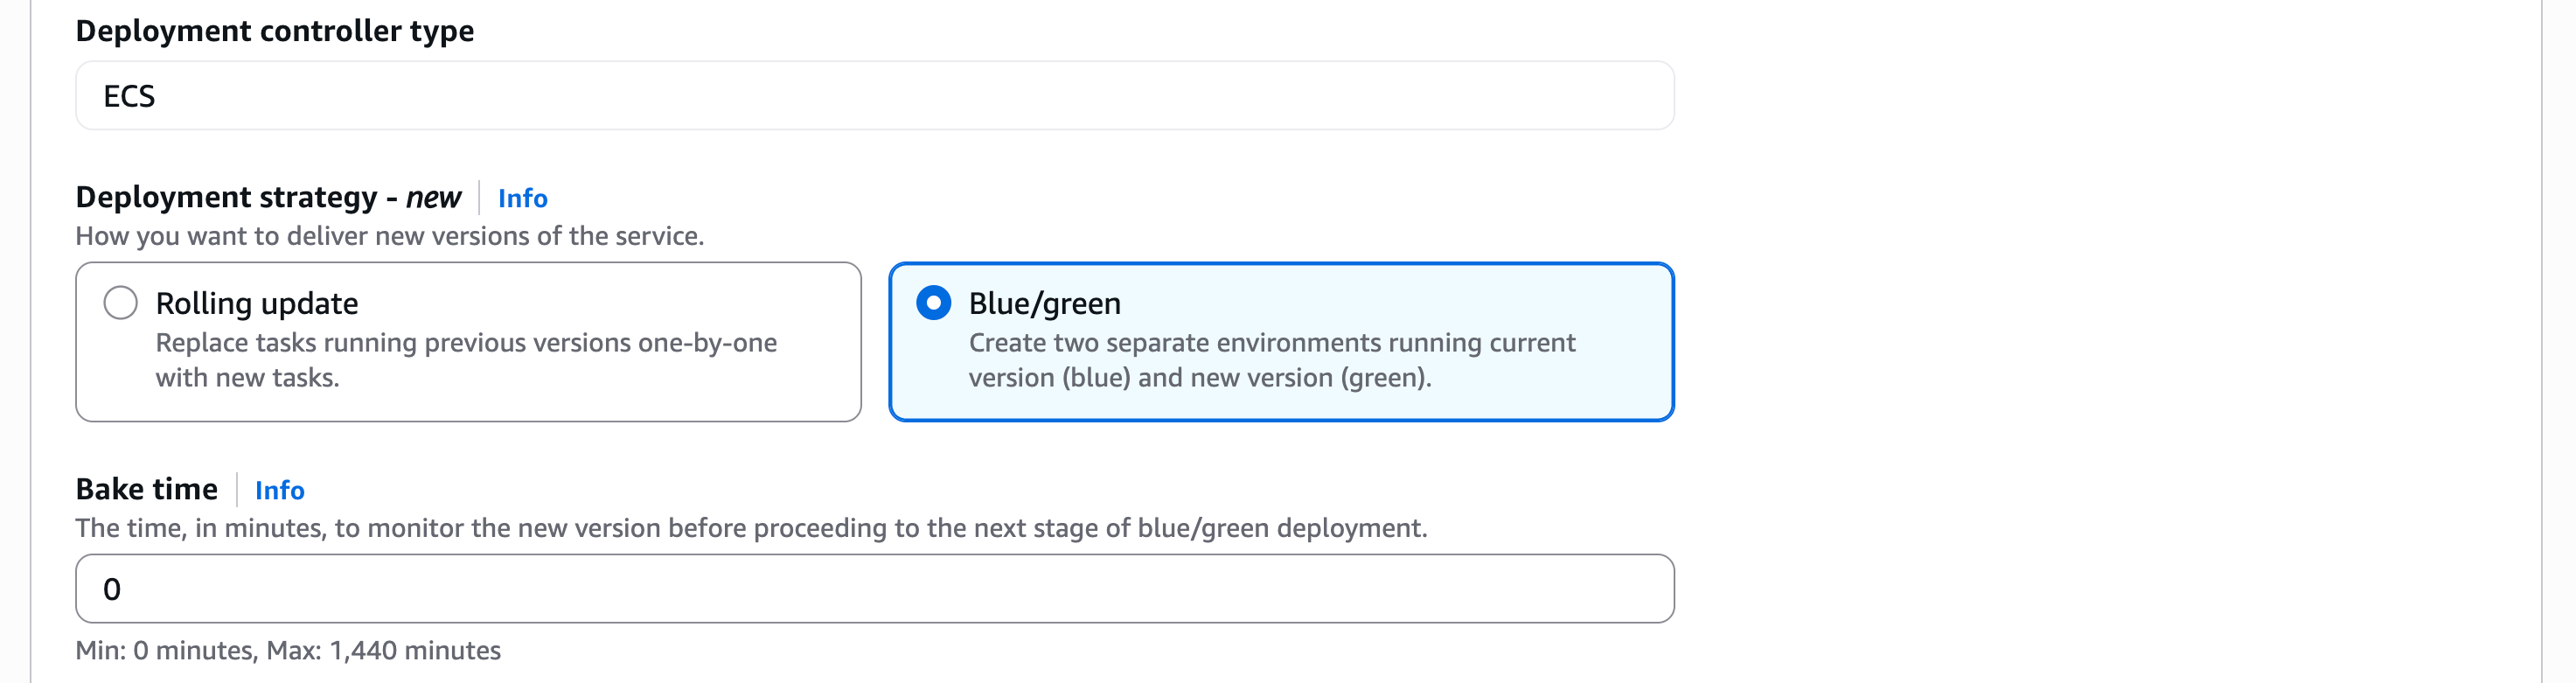
For this demonstration, I want to deploy a new version of my application using the blue/green strategy to minimize risk. First, I need to configure my ECS service to use blue/green deployments. I can do this through the ECS console, AWS Command Line Interface (AWS CLI), or using infrastructure as code.

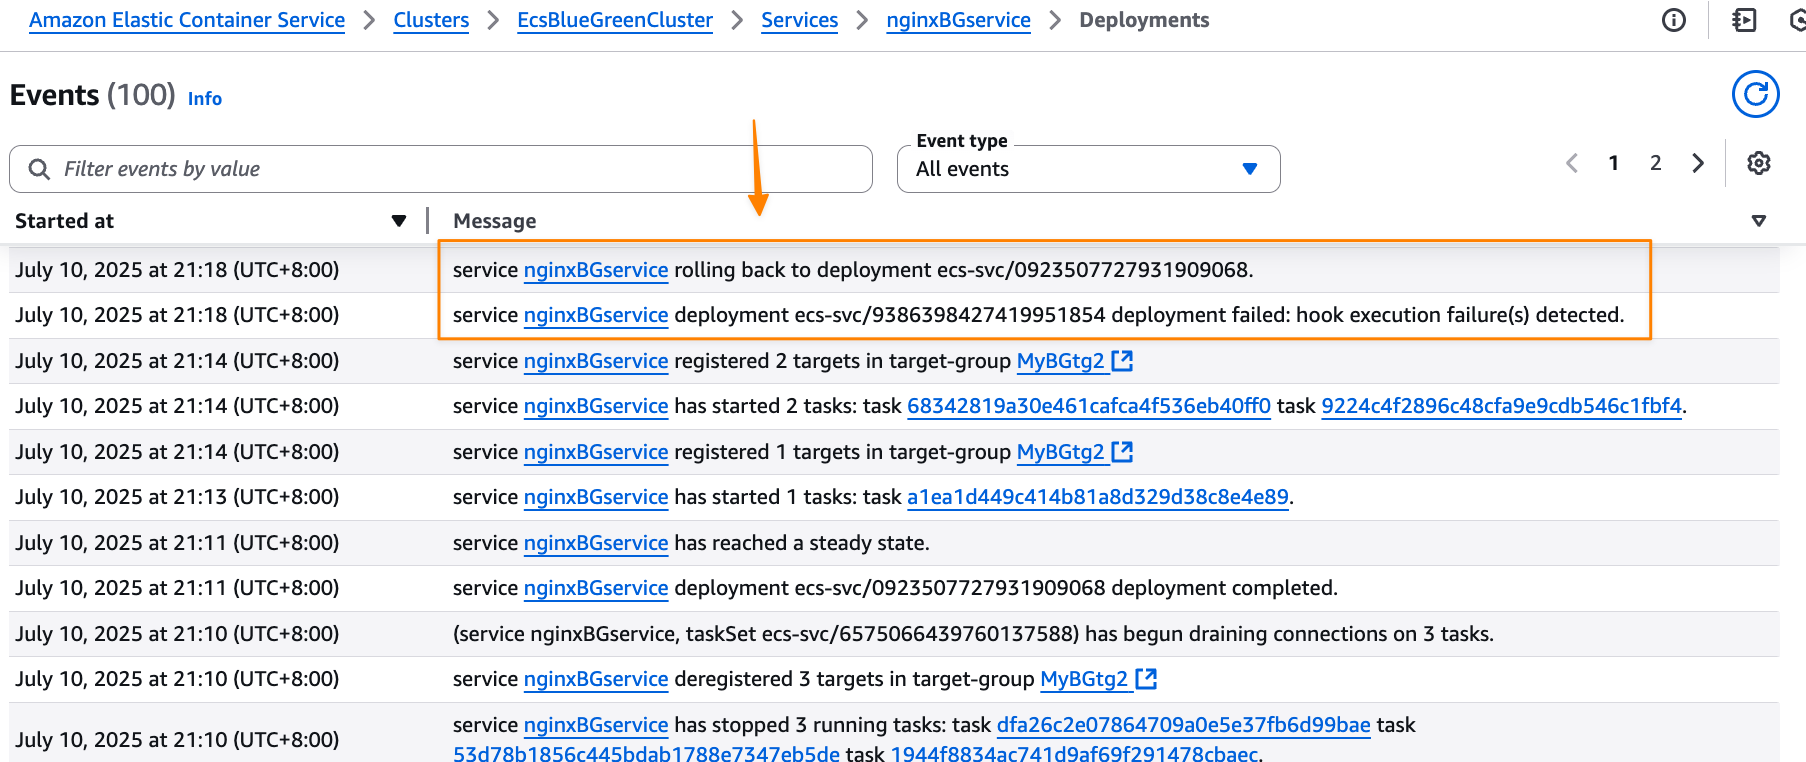
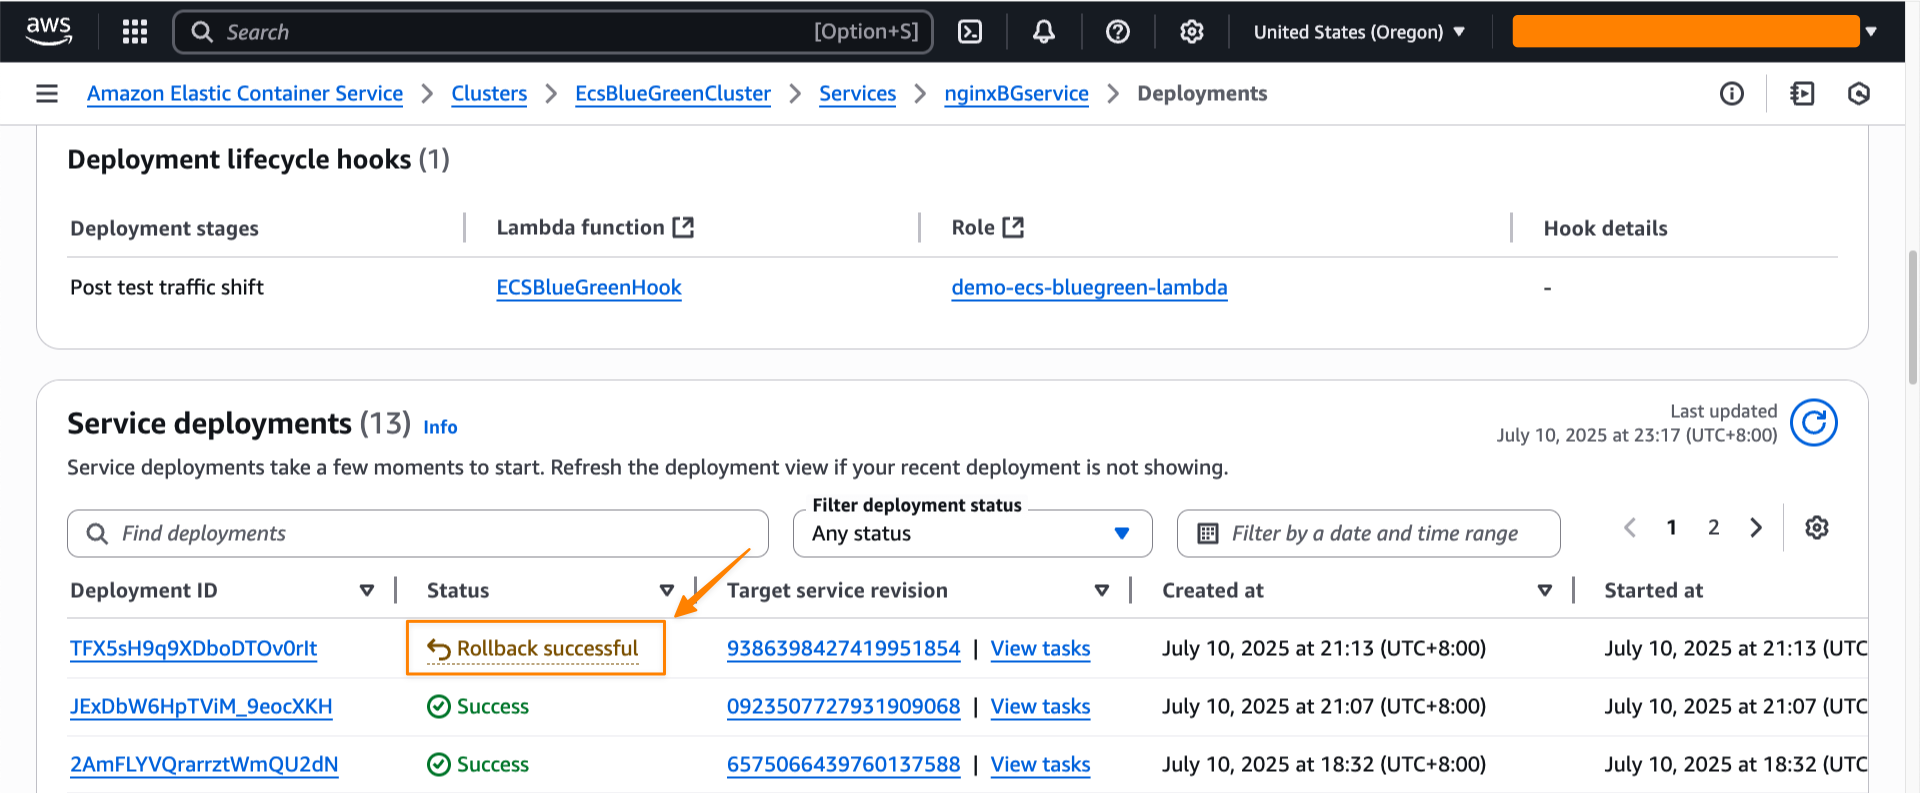
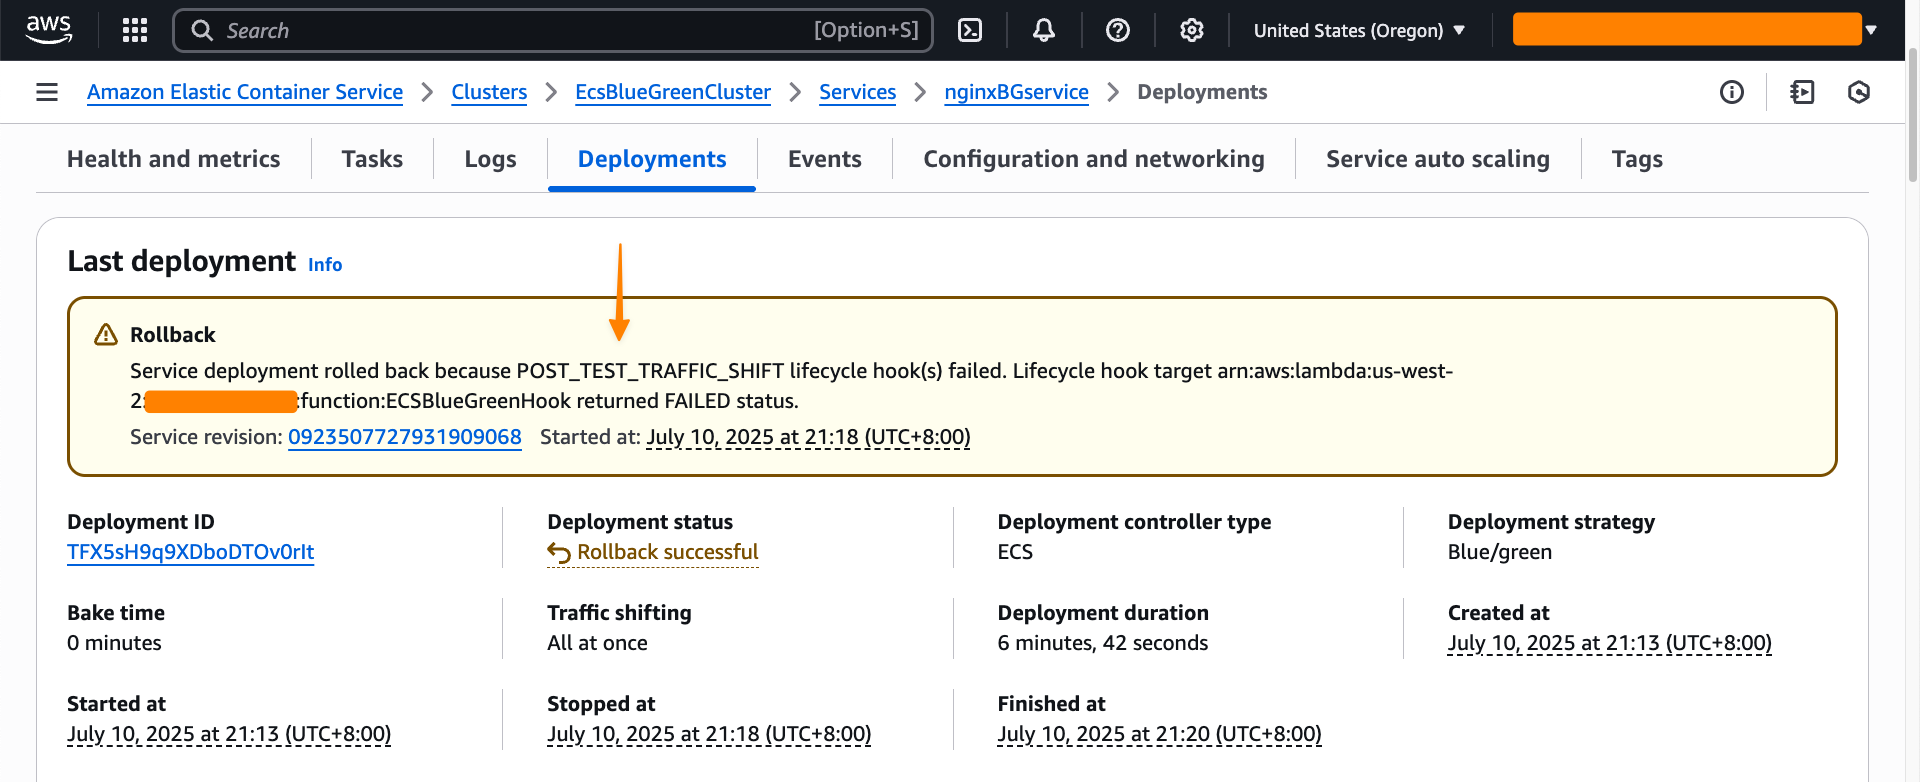
Using the Amazon ECS console, I create a new service and configure it as usual:

In the Deployment Options section, I choose ECS as the Deployment controller type, then Blue/green as the Deployment strategy. Bake time is the time after the production traffic has shifted to green, when instant rollback to blue is available. When the bake time expires, blue tasks are removed.

We’re also introducing deployment lifecycle hooks. These are event-driven mechanisms you can use to augment the deployment workflow. I can select which AWS Lambda function I’d like to use as a deployment lifecycle hook. The Lambda function can perform the required business logic, but it must return a hook status.

Amazon ECS supports the following lifecycle hooks during blue/green deployments. You can learn more about each stage on the Deployment lifecycle stages page.

  • Pre scale up
  • Post scale up
  • Production traffic shift
  • Test traffic shift
  • Post production traffic shift
  • Post test traffic shift

For my application, I want to test when the test traffic shift is complete and the green service handles all of the test traffic. Since there’s no end-user traffic, a rollback at this stage will have no impact on users. This makes Post test traffic shift suitable for my use case as I can test it first with my Lambda function.

Switching context for a moment, let’s focus on the Lambda function that I use to validate the deployment before allowing it to proceed. In my Lambda function as a deployment lifecycle hook, I can perform any business logic, such as synthetic testing, calling another API, or querying metrics.

Within the Lambda function, I must return a hookStatus. A hookStatus can be SUCCESSFUL, which will move the process to the next step. If the status is FAILED, it rolls back to the blue deployment. If it’s IN_PROGRESS, then Amazon ECS retries the Lambda function in 30 seconds.

In the following example, I set up my validation with a Lambda function that performs file upload as part of a test suite for my application.

import json
import urllib3
import logging
import base64
import os

# Configure logging
logger = logging.getLogger()
logger.setLevel(logging.DEBUG)

# Initialize HTTP client
http = urllib3.PoolManager()

def lambda_handler(event, context):
    """
    Validation hook that tests the green environment with file upload
    """
    logger.info(f"Event: {json.dumps(event)}")
    logger.info(f"Context: {context}")
    
    try:
        # In a real scenario, you would construct the test endpoint URL
        test_endpoint = os.getenv("APP_URL")
        
        # Create a test file for upload
        test_file_content = "This is a test file for deployment validation"
        test_file_data = test_file_content.encode('utf-8')
        
        # Prepare multipart form data for file upload
        fields = {
            'file': ('test.txt', test_file_data, 'text/plain'),
            'description': 'Deployment validation test file'
        }
        
        # Send POST request with file upload to /process endpoint
        response = http.request(
            'POST', 
            test_endpoint,
            fields=fields,
            timeout=30
        )
        
        logger.info(f"POST /process response status: {response.status}")
        
        # Check if response has OK status code (200-299 range)
        if 200 <= response.status < 300:
            logger.info("File upload test passed - received OK status code")
            return {
                "hookStatus": "SUCCEEDED"
            }
        else:
            logger.error(f"File upload test failed - status code: {response.status}")
            return {
                "hookStatus": "FAILED"
            }
            
    except Exception as error:
        logger.error(f"File upload test failed: {str(error)}")
        return {
            "hookStatus": "FAILED"
        }

When the deployment reaches the lifecycle stage that is associated with the hook, Amazon ECS automatically invokes my Lambda function with deployment context. My validation function can run comprehensive tests against the green revision—checking application health, running integration tests, or validating performance metrics. The function then signals back to ECS whether to proceed or abort the deployment.

As I chose the blue/green deployment strategy, I also need to configure the load balancers and/or Amazon ECS Service Connect. In the Load balancing section, I select my Application Load Balancer.

In the Listener section, I use an existing listener on port 80 and select two Target groups.

Happy with this configuration, I create the service and wait for ECS to provision my new service.

Testing blue/green deployments
Now, it’s time to test my blue/green deployments. For this test, Amazon ECS will trigger my Lambda function after the test traffic shift is completed. My Lambda function will return FAILED in this case as it performs file upload to my application, but my application doesn’t have this capability.

I update my service and check Force new deployment, knowing the blue/green deployment capability will roll back if it detects a failure. I select this option because I haven’t modified the task definition but still need to trigger a new deployment.

At this stage, I have both blue and green environments running, with the green revision handling all the test traffic. Meanwhile, based on Amazon CloudWatch Logs of my Lambda function, I also see that the deployment lifecycle hooks work as expected and emit the following payload:

[INFO]	2025-07-10T13:15:39.018Z	67d9b03e-12da-4fab-920d-9887d264308e	Event: 
{
    "executionDetails": {
        "testTrafficWeights": {},
        "productionTrafficWeights": {},
        "serviceArn": "arn:aws:ecs:us-west-2:123:service/EcsBlueGreenCluster/nginxBGservice",
        "targetServiceRevisionArn": "arn:aws:ecs:us-west-2:123:service-revision/EcsBlueGreenCluster/nginxBGservice/9386398427419951854"
    },
    "executionId": "a635edb5-a66b-4f44-bf3f-fcee4b3641a5",
    "lifecycleStage": "POST_TEST_TRAFFIC_SHIFT",
    "resourceArn": "arn:aws:ecs:us-west-2:123:service-deployment/EcsBlueGreenCluster/nginxBGservice/TFX5sH9q9XDboDTOv0rIt"
}

As expected, my AWS Lambda function returns FAILED as hookStatus because it failed to perform the test.

[ERROR]	2025-07-10T13:18:43.392Z	67d9b03e-12da-4fab-920d-9887d264308e	File upload test failed: HTTPConnectionPool(host='xyz.us-west-2.elb.amazonaws.com', port=80): Max retries exceeded with url: / (Caused by ConnectTimeoutError(<urllib3.connection.HTTPConnection object at 0x7f8036273a80>, 'Connection to xyz.us-west-2.elb.amazonaws.com timed out. (connect timeout=30)'))

Because the validation wasn’t completed successfully, Amazon ECS tries to roll back to the blue version, which is the previous working deployment version. I can monitor this process through ECS events in the Events section, which provides detailed visibility into the deployment progress.

Amazon ECS successfully rolls back the deployment to the previous working version. The rollback happens near-instantaneously because the blue revision remains running and ready to receive production traffic. There is no end-user impact during this process, as production traffic never shifted to the new application version—ECS simply rolled back test traffic to the original stable version. This eliminates the typical deployment downtime associated with traditional rolling deployments.

I can also see the rollback status in the Last deployment section.

Throughout my testing, I observed that the blue/green deployment strategy provides consistent and predictable behavior. Furthermore, the deployment lifecycle hooks provide more flexibility to control the behavior of the deployment. Each service revision maintains immutable configuration including task definition, load balancer settings, and Service Connect configuration. This means that rollbacks restore exactly the same environment that was previously running.

Additional things to know
Here are a couple of things to note:

  • Pricing – The blue/green deployment capability is included with Amazon ECS at no additional charge. You pay only for the compute resources used during the deployment process.
  • Availability – This capability is available in all commercial AWS Regions.

Get started with blue/green deployments by updating your Amazon ECS service configuration in the Amazon ECS console.

Happy deploying!
Donnie

New Amazon EC2 P6e-GB200 UltraServers accelerated by NVIDIA Grace Blackwell GPUs for the highest AI performance

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/new-amazon-ec2-p6e-gb200-ultraservers-powered-by-nvidia-grace-blackwell-gpus-for-the-highest-ai-performance/

Today, we’re announcing the general availability of Amazon Elastic Compute Cloud (Amazon EC2) P6e-GB200 UltraServers, accelerated by NVIDIA GB200 NVL72 to offer the highest GPU performance for AI training and inference. Amazon EC2 UltraServers connect multiple EC2 instances using a dedicated, high-bandwidth, and low-latency accelerator interconnect across these instances.

The NVIDIA Grace Blackwell Superchips connect two high-performance NVIDIA Blackwell tensor core GPUs and an NVIDIA Grace CPU based on Arm architecture using the NVIDIA NVLink-C2C interconnect. Each Grace Blackwell Superchip delivers 10 petaflops of FP8 compute (without sparsity) and up to 372 GB HBM3e memory. With the superchip architecture, GPU and CPU are colocated within one compute module, increasing bandwidth between GPU and CPU significantly compared to current generation EC2 P5en instances.

With EC2 P6e-GB200 UltraServers, you can access up to 72 NVIDIA Blackwell GPUs within one NVLink domain to use 360 petaflops of FP8 compute (without sparsity) and 13.4 TB of total high bandwidth memory (HBM3e). Powered by the AWS Nitro System, P6e-GB200 UltraServers are deployed in EC2 UltraClusters to securely and reliably scale to tens of thousands of GPUs.

EC2 P6e-GB200 UltraServers deliver up to 28.8 Tbps of total Elastic Fabric Adapter (EFAv4) networking. EFA is also coupled with NVIDIA GPUDirect RDMA to enable low-latency GPU-to-GPU communication between servers with operating system bypass.

EC2 P6e-GB200 UltraServers specifications
EC2 P6e-GB200 UltraServers are available in sizes ranging from 36 to 72 GPUs under NVLink. Here are the specs for EC2 P6e-GB200 UltraServers:

UltraServer type GPUs
GPU
memory (GB)
vCPUs Instance memory
(GiB)
Instance storage (TB) Aggregate EFA Network Bandwidth (Gbps) EBS bandwidth (Gbps)
u-p6e-gb200x36 36 6660 1296 8640 202.5 14400 540
u-p6e-gb200x72 72 13320 2592 17280 405 28800 1080

P6e-GB200 UltraServers are ideal for the most compute and memory intensive AI workloads, such as training and inference of frontier models, including mixture of experts models and reasoning models, at the trillion-parameter scale.

You can build agentic and generative AI applications, including question answering, code generation, video and image generation, speech recognition, and more.

P6e-GB200 UltraServers in action
You can use EC2 P6e-GB200 UltraServers in the Dallas Local Zone through EC2 Capacity Blocks for ML. The Dallas Local Zone (us-east-1-dfw-2a) is an extension of the US East (N. Virginia) Region.

To reserve your EC2 Capacity Blocks, choose Capacity Reservations on the Amazon EC2 console. You can select Purchase Capacity Blocks for ML and then choose your total capacity and specify how long you need the EC2 Capacity Block for u-p6e-gb200x36 or u-p6e-gb200x72 UltraServers.

Once Capacity Block is successfully scheduled, it is charged up front and its price doesn’t change after purchase. The payment will be billed to your account within 12 hours after you purchase the EC2 Capacity Blocks. To learn more, visit Capacity Blocks for ML in the Amazon EC2 User Guide.

To run instances within your purchased Capacity Block, you can use AWS Management Console, AWS Command Line Interface (AWS CLI) or AWS SDKs. On the software side, you can start with the AWS Deep Learning AMIs. These images are preconfigured with the frameworks and tools that you probably already know and use: PyTorch, JAX, and a lot more.

You can also integrate EC2 P6e-GB200 UltraServers seamlessly with various AWS managed services. For example:

  • Amazon SageMaker Hyperpod provides managed, resilient infrastructure that automatically handles the provisioning and management of P6e-GB200 UltraServers, replacing faulty instances with preconfigured spare capacity within the same NVLink domain to maintain performance.
  • Amazon Elastic Kubernetes Services (Amazon EKS) allows one managed node group to span across multiple P6e-GB200 UltraServers as nodes, automating their provisioning and lifecycle management within Kubernetes clusters. You can use EKS topology-aware routing for P6e-GB200 UltraServers, enabling optimal placement of tightly coupled components of distributed workloads within a single UltraServer’s NVLink-connected instances.
  • Amazon FSx for Lustre file systems provide data access for P6e-GB200 UltraServers at the hundreds of GB/s of throughput and millions of input/output operations per second (IOPS) required for large-scale HPC and AI workloads. For fast access to large datasets, you can use up to 405 TB of local NVMe SSD storage or virtually unlimited cost-effective storage with Amazon Simple Storage Service (Amazon S3).

Now available
Amazon EC2 P6e-GB200 UltraServers are available today in the Dallas Local Zone (us-east-1-dfw-2a) through EC2 Capacity Blocks for ML. For more information, visit the Amazon EC2 pricing page.

Give Amazon EC2 P6e-GB200 UltraServers a try in the Amazon EC2 console. To learn more, visit the Amazon EC2 P6e instances page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

Channy

New Amazon EC2 C8gn instances powered by AWS Graviton4 offering up to 600Gbps network bandwidth

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/new-amazon-ec2-c8gn-instances-powered-by-aws-graviton4-offering-up-to-600gbps-network-bandwidth/

Today, we’re announcing the general availability of Amazon Elastic Compute Cloud (Amazon EC2) C8gn network optimized instances powered by AWS Graviton4 processors and the latest 6th generation AWS Nitro Card. EC2 C8gn instances deliver up to 600Gbps network bandwidth, the highest bandwidth among EC2 network optimized instances.

You can use C8gn instances to run the most demanding network intensive workloads, such as security and network virtual appliances (virtual firewalls, routers, load balancers, proxy servers, DDoS appliances), data analytics, and tightly-coupled cluster computing jobs.

EC2 C8gn instances specifications
C8gn instances provide up to 192 vCPUs and 384 GiB memory, and offer up to 30 percent higher compute performance compared Graviton3-based EC2 C7gn instances.

Here are the specs for C8gn instances:

Instance Name vCPUs Memory (GiB) Network Bandwidth (Gbps) EBS Bandwidth (Gbps)
c8gn.medium 1 2 Up to 25 Up to 10
c8gn.large 2 4 Up to 30 Up to 10
c8gn.xlarge 4 8 Up to 40 Up to 10
c8gn.2xlarge 8 16 Up to 50 Up to 10
c8gn.4xlarge 16 32 50 10
c8gn.8xlarge 32 64 100 20
c8gn.12xlarge 48 96 150 30
c8gn.16xlarge 64 128 200 40
c8gn.24xlarge 96 192 300 60
c8gn.metal-24xl 96 192 300 60
c8gn.48xlarge 192 384 600 60
c8gn.metal-48xl 192 384 600 60

You can launch C8gn instances through the AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS SDKs.

If you’re using C7gn instances now, you will have straightforward experience migrating network intensive workloads to C8gn instances because the new instances offer similar vCPU and memory ratios. To learn more, check out the collection of Graviton resources to help you start migrating your applications to Graviton instance types.

You can also visit the Level up your compute with AWS Graviton page to begin your Graviton adoption journey.

Now available
Amazon EC2 C8gn instances are available today in US East (N. Virginia) and US West (Oregon) Regions. Two metal instance sizes are only available in US East (N. Virginia) Region. These instances can be purchased as On-Demand, Savings Plan, Spot instances, or as Dedicated instances and Dedicated hosts.

Give C8gn instances a try in the Amazon EC2 console. To learn more, refer to the Amazon EC2 C8g instance page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

Channy

Amazon Linux 2023 achieves FIPS 140-3 validation

Post Syndicated from Mahak Arora original https://aws.amazon.com/blogs/compute/amazon-linux-2023-achieves-fips-140-3-validation/

AWS announced that Amazon Linux 2023 (AL2023) has achieved Federal Information Processing Standards (FIPS) 140-3 Level 1 validation of our cryptographic modules, marking a significant milestone in our commitment to providing secure, compliant operating system options for regulated workloads. FIPS certified modules are particularly important for US and Canadian government workloads, healthcare applications requiring HIPAA compliance, financial services, defense contractors, and other regulated industries. FIPS 140-3, which supersedes FIPS 140-2, represents the latest government security standard for cryptographic modules, jointly validated by the National Institute of Standards and Technology (NIST) and the Canadian Centre for Cyber Security (CCCS) through the Cryptographic Module Validation Program (CMVP). The validation follows the rigorous requirements outlined in the FIPS 140-3 standard and encompasses critical cryptographic modules including the OpenSSL, Linux Kernel Cryptographic API, NSS, GnuTLS, and Libgcrypt.

These modules have been extensively tested to have robust security capabilities such as approved cryptographic algorithms, secure key management, strong entropy generation, and protected memory boundaries. The validation process was conducted by a NIST-accredited lab, and further reviewed by the Cryptographic Module Validation Program (CMVP). Additionally, the certificate details can be verified on the CMVP Active Validation List.

In order to enable FIPS mode on AL2023, customers can refer to our FIPS Mode enablement guide on AL2023. Amazon Linux maintains its compliance information through AWS Compliance Programs portal for FIPS- 140-3 and official NIST Guidelines and Compliance FAQs, for meeting global regulatory requirements. For regular updates and best practices, follow the AWS Security Blog, FIPS related FAQs on Amazon Linux 2 and Amazon Linux 2023 providing detailed configuration steps and operational guidance for regulated environments. You can also reach out to your AWS account team for help finding the resources you need.

If you have questions about this post, contact AWS Support.

Announcing up to 45% price reduction for Amazon EC2 NVIDIA GPU-accelerated instances

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/announcing-up-to-45-price-reduction-for-amazon-ec2-nvidia-gpu-accelerated-instances/

Customers across industries are harnessing the power of generative AI on AWS to boost employee productivity, deliver exceptional customer experiences, and streamline business processes. However, the growth in demand for GPU capacity has outpaced industry-wide supply, making GPUs a scarce resource and increasing the cost of securing them.

As Amazon Web Services (AWS) grows, we work hard to lower our costs so that we can pass those savings back to our customers. Regular price reductions on AWS services have been a standard way for AWS to pass on the economic efficiencies gained from our scale back to our customers.

Today, we’re announcing up to 45 percent price reduction for Amazon Elastic Compute Cloud (Amazon EC2) NVIDIA GPU-accelerated instances: P4 (P4d and P4de) and P5 (P5 and P5en) instance types. This price reduction to On-Demand and Savings Plan pricing applies to all Regions where these instances are available. The pricing reduction applies to On-Demand purchases beginning June 1 and to Savings Plan purchases effective after June 4.

Here is a table of price reductions percentage (%) from May 31, 2025 baseline prices by instance types and pricing plans:

Instance type NVIDIA GPUs On-Demand EC2 Instance Savings Plans Compute Savings Plans
1 year 3 years 1 year 3 years
P4d A100 33% 31% 25% 31%
P4de A100 33% 31% 25% 31%
P5 H100 44% 45% 44% 25%
P5en H200 25% 26% 25%

Savings Plans are a flexible pricing model that offer low prices on compute usage, in exchange for a commitment to a consistent amount of usage (measured in $/hour) for a 1- or 3- year term. We offers two types of Savings Plans:

  • EC2 Instance Savings Plans provide the lowest prices, offering savings in exchange for commitment to usage of individual instance families in a Region (for example, P5 usage in the US (N. Virginia) Region).
  • Compute Savings Plans provide the most flexibility and help to reduce your costs regardless of instance family, size, Availability Zones, and Regions (for example, from P4d to P5en instances, shift a workload between US Regions).

To provide increased accessibility to reduced pricing, we are making at-scale On-Demand capacity available for:

  • P4d instances in the Asia Pacific (Seoul), Asia Pacific (Sydney), Canada (Central), and Europe (London) Regions
  • P4de instances in the US East (N. Virginia) Region
  • P5 instances in the Asia Pacific (Mumbai), Asia Pacific (Tokyo), Asia Pacific (Jakarta), and South America (São Paulo) Regions
  • P5en instances in the Asia Pacific (Mumbai), Asia Pacific (Tokyo), and Asia Pacific (Jakarta) Regions

We are also now delivering Amazon EC2 P6-B200 instances through Savings Plan to support large scale deployments, which became available on May 15, 2025 at launch only through EC2 Capacity Blocks for ML. EC2 P6-B200 instances, powered by NVIDIA Blackwell GPUs, accelerate a broad range of GPU-enabled workloads but are especially well-suited for large-scale distributed AI training and inferencing.

These pricing updates reflect the AWS commitment to making advanced GPU computing more accessible while passing cost savings directly to customers.

Give Amazon EC2 NVIDIA GPU-accelerated instances a try in the Amazon EC2 console. To learn more about these pricing updates, visit Amazon EC2 Pricing page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

Channy

Enhance AI-assisted development with Amazon ECS, Amazon EKS and AWS Serverless MCP server

Post Syndicated from Elizabeth Fuentes original https://aws.amazon.com/blogs/aws/enhance-ai-assisted-development-with-amazon-ecs-amazon-eks-and-aws-serverless-mcp-server/

Today, we’re introducing specialized Model Context Protocol (MCP) servers for Amazon Elastic Container Service (Amazon ECS), Amazon Elastic Kubernetes Service (Amazon EKS), and AWS Serverless, now available in the AWS Labs GitHub repository. These open source solutions extend AI development assistants capabilities with real-time, contextual responses that go beyond their pre-trained knowledge. While Large Language Models (LLM) within AI assistants rely on public documentation, MCP servers deliver current context and service-specific guidance to help you prevent common deployment errors and provide more accurate service interactions.

You can use these open source solutions to develop applications faster, using up-to-date knowledge of Amazon Web Services (AWS) capabilities and configurations during the build and deployment process. Whether you’re writing code in your integrated development environment (IDE), or debugging production issues, these MCP servers support AI code assistants with deep understanding of Amazon ECS, Amazon EKS, and AWS Serverless capabilities, accelerating the journey from code to production. They work with popular AI-enabled IDEs, including Amazon Q Developer on the command line (CLI), to help you build and deploy applications using natural language commands.

  • The Amazon ECS MCP Server containerizes and deploys applications to Amazon ECS within minutes by configuring all relevant AWS resources, including load balancers, networking, auto-scaling, monitoring, Amazon ECS task definitions, and services. Using natural language instructions, you can manage cluster operations, implement auto-scaling strategies, and use real-time troubleshooting capabilities to identify and resolve deployment issues quickly.
  • For Kubernetes environments, the Amazon EKS MCP Server provides AI assistants with up-to-date, contextual information about your specific EKS environment. It offers access to the latest EKS features, knowledge base, and cluster state information. This gives AI code assistants more accurate, tailored guidance throughout the application lifecycle, from initial setup to production deployment.
  • The AWS Serverless MCP Server enhances the serverless development experience by providing AI coding assistants with comprehensive knowledge of serverless patterns, best practices, and AWS services. Using AWS Serverless Application Model Command Line Interface (AWS SAM CLI) integration, you can handle events and deploy infrastructure while implementing proven architectural patterns. This integration streamlines function lifecycles, service integrations, and operational requirements throughout your application development process. The server also provides contextual guidance for infrastructure as code decisions, AWS Lambda specific best practices, and event schemas for AWS Lambda event source mappings.

Let’s see it in action
If this is your first time using AWS MCP servers, visit the Installation and Setup guide in the AWS Labs GitHub repository to installation instructions. Once installed, add the following MCP server configuration to your local setup:

Install Amazon Q for command line and add the configuration to ~/.aws/amazonq/mcp.json. If you’re already an Amazon Q CLI user, add only the configuration.

{
  "mcpServers": {
    "awslabs.aws-serverless-mcp":  {
      "command": "uvx",
      "timeout": 60,
      "args": ["awslabs.aws_serverless_mcp_server@latest"],
    },
    "awslabs.ecs-mcp-server": {
      "disabled": false,
      "command": "uv",
      "timeout": 60,
      "args": ["awslabs.ecs-mcp-server@latest"],
    },
    "awslabs.eks-mcp-server": {
      "disabled": false,
      "timeout": 60,
      "command": "uv",
      "args": ["awslabs.eks-mcp-server@latest"],
    }
  }
}

For this demo I’m going to use the Amazon Q CLI to create an application that understands video using 02_using_converse_api.ipynb from Amazon Nova model cookbook repository as sample code. To do this, I send the following prompt:

I want to create a backend application that automatically extracts metadata and understands the content of images and videos uploaded to an S3 bucket and stores that information in a database. I'd like to use a serverless system for processing. Could you generate everything I need, including the code and commands or steps to set up the necessary infrastructure, for it to work from start to finish? - Use 02_using_converse_api.ipynb as example code for the image and video understanding.

Amazon Q CLI identifies the necessary tools, including the MCP serverawslabs.aws-serverless-mcp-server. Through a single interaction, the AWS Serverless MCP server determines all requirements and best practices for building a robust architecture.

I ask to Amazon Q CLI that build and test the application, but encountered an error. Amazon Q CLI quickly resolved the issue using available tools. I verified success by checking the record created in the Amazon DynamoDB table and testing the application with the dog2.jpeg file.

To enhance video processing capabilities, I decided to migrate my media analysis application to a containerized architecture. I used this prompt:

I'd like you to create a simple application like the media analysis one, but instead of being serverless, it should be containerized. Please help me build it in a new CDK stack.

Amazon Q Developer begins building the application. I took advantage of this time to grab a coffee. When I returned to my desk, coffee in hand, I was pleasantly surprised to find the application ready. To ensure everything was up to current standards, I simply asked:

please review the code and all app using the awslabsecs_mcp_server tools 

Amazon Q Developer CLI gives me a summary with all the improvements and a conclusion.

I ask it to make all the necessary changes, once ready I ask Amazon Q developer CLI to deploy it in my account, all using natural language.

After a few minutes, I review that I have a complete containerized application from the S3 bucket to all the necessary networking.

I ask Amazon Q developer CLI to test the app send it the-sea.mp4 video file and received a timed out error, so Amazon Q CLI decides to use the fetch_task_logs from awslabsecs_mcp_server tool to review the logs, identify the error and then fix it.

After a new deployment, I try it again, and the application successfully processed the video file

I can see the records in my Amazon DynamoDB table.

To test the Amazon EKS MCP server, I have code for a web app in the auction-website-main folder and I want to build a web robust app, for that I asked Amazon Q CLI to help me with this prompt:

Create a web application using the existing code in the auction-website-main folder. This application will grow, so I would like to create it in a new EKS cluster

Once the Docker file is created, Amazon Q CLI identifies generate_app_manifests from awslabseks_mcp_server as a reliable tool to create a Kubernetes manifests for the application.

Then create a new EKS cluster using the manage_eks_staks tool.

Once the app is ready, the Amazon Q CLI deploys it and gives me a summary of what it created.

I can see the cluster status in the console.

After a few minutes and resolving a couple of issues using the search_eks_troubleshoot_guide tool the application is ready to use.

Now I have a Kitties marketplace web app, deployed on Amazon EKS using only natural language commands through Amazon Q CLI.

Get started today
Visit the AWS Labs GitHub repository to start using these AWS MCP servers and enhance your AI-powered developmen there. The repository includes implementation guides, example configurations, and additional specialized servers to run AWS Lambda function, which transforms your existing AWS Lambda functions into AI-accessible tools without code modifications, and Amazon Bedrock Knowledge Bases Retrieval MCP server, which provides seamless access to your Amazon Bedrock knowledge bases. Other AWS specialized servers in the repository include documentation, example configurations, and implementation guides to begin building applications with greater speed and reliability.

To learn more about MCP Servers for AWS Serverless and Containers and how they can transform your AI-assisted application development, visit the Introducing AWS Serverless MCP Server: AI-powered development for modern applications, Automating AI-assisted container deployments with the Amazon ECS MCP Server, and Accelerating application development with the Amazon EKS MCP server deep-dive blogs.

— Eli

Amazon Inspector enhances container security by mapping Amazon ECR images to running containers

Post Syndicated from Elizabeth Fuentes original https://aws.amazon.com/blogs/aws/amazon-inspector-enhances-container-security-by-mapping-amazon-ecr-images-to-running-containers/

When running container workloads, you need to understand how software vulnerabilities create security risks for your resources. Until now, you could identify vulnerabilities in your Amazon Elastic Container Registry (Amazon ECR) images, but couldn’t determine if these images were active in containers or track their usage. With no visibility if these images were being used on running clusters, you had limited ability to prioritize fixes based on actual deployment and usage patterns.

Starting today, Amazon Inspector offers two new features that enhance vulnerability management, giving you a more comprehensive view of your container images. First, Amazon Inspector now maps Amazon ECR images to running containers, enabling security teams to prioritize vulnerabilities based on containers currently running in your environment. With these new capabilities, you can analyze vulnerabilities in your Amazon ECR images and prioritize findings based on whether they are currently running and when they last ran in your container environment. Additionally, you can see the cluster Amazon Resource Name (ARN), number EKS pods or ECS tasks where an image is deployed, helping you prioritize fixes based on usage and severity.

Second, we’re extending vulnerability scanning support to minimal base images including scratch, distroless, and Chainguard images, and extending support for additional ecosystems including Go toolchain, Oracle JDK & JRE, Amazon Corretto, Apache Tomcat, Apache httpd, WordPress (core, themes, plugins), and Puppeteer, helping teams maintain robust security even in highly optimized container environments.

Through continual monitoring and tracking of images running on containers, Amazon Inspector helps teams identify which container images are actively running in their environment and where they’re deployed, detecting Amazon ECR images running on containers in Amazon Elastic Container Service (Amazon ECS) and Amazon Elastic Kubernetes Service (Amazon EKS), and any associated vulnerabilities. This solution supports teams managing Amazon ECR images across single AWS accounts, cross-account scenarios, and AWS Organizations with delegated administrator capabilities, enabling centralized vulnerability management based on container images running patterns.

Let’s see it in action
Amazon ECR image scanning helps identify vulnerabilities in your container images through enhanced scanning, which integrates with Amazon Inspector to provide automated, continual scanning of your repositories. To use this new feature you have to enable enhanced scanning through the Amazon ECR console, you can do it by following the steps in the Configuring enhanced scanning for images in Amazon ECR documentation page. I already have Amazon ECR enhanced scanning, so I don’t have to do any action.

In the Amazon Inspector console, I navigate to General settings and select ECR scanning settings from the navigation panel. Here, I can configure the new Image re-scan mode settings by choosing between Last in-use date and Last pull date. I leave it as it is by default with Last in-use date and set the Image last in use date to 14 days. These settings make it so that Inspector monitors my images based on when they were running in the last 14 days in my Amazon ECS or Amazon EKS environments. After applying these settings, Amazon Inspector starts tracking information about images running on containers and incorporating it into vulnerability findings, helping me focus on images actively running in containers in my environment.

After it’s configured, I can view information about images running on containers in the Details menu, where I can see last in-use and pull dates, along with EKS pods or ECS tasks count.

When selecting the number of Deployed ECS Tasks/EKS Pods, I can see the cluster ARN, last use dates, and Type for each image.

For cross-account visibility demonstration, I have a repository with EKS pods deployed in two accounts. In the Resources coverage menu, I navigate to Container repositories, select my repository name and choose the Image tag. As before, I can see the number of deployed EKS pods/ECS tasks.

When I select the number of deployed EKS pods/ECS tasks, I can see that it is running in a different account.

In the Findings menu, I can review any vulnerabilities, and by selecting one, I can find the Last in use date and Deployed ECS Tasks/EKS Pods involved in the vulnerability under Resource affected data, helping me prioritize remediation based on actual usage.

In the All Findings menu, you can now search for vulnerabilities within account management, using filters such as Account ID, Image in use count and Image last in use at.

Key features and considerations
Monitoring based on container image lifecycle – Amazon Inspector now determines image activity based on: image push date ranging duration 14, 30, 60, 90, or 180 days or lifetime, image pull date from 14, 30, 60, 90, or 180 days, stopped duration from never to 14, 30, 60, 90, or 180 days and status of image running on the container. This flexibility lets organizations tailor their monitoring strategy based on actual container image usage rather than only repository events. For Amazon EKS and Amazon ECS workloads, last in use, push and pull duration are set to 14 days, which is now the default for new customers.

Image runtime-aware finding details – To help prioritize remediation efforts, each finding in Amazon Inspector now includes the lastInUseAt date and InUseCount, indicating when an image was last running on the containers and the number of deployed EKS pods/ ECS tasks currently using it. Amazon Inspector monitors both Amazon ECR last pull date data and images running on Amazon ECS tasks or Amazon EKS pods container data for all accounts, updating this information at least once daily. Amazon Inspector integrates these details into all findings reports and seamlessly works with Amazon EventBridge. You can filter findings based on the lastInUseAt field using rolling window or fixed range options, and you can filter images based on their last running date within the last 14, 30, 60, or 90 days.

Comprehensive security coverage – Amazon Inspector now provides unified vulnerability assessments for both traditional Linux distributions and minimal base images including scratch, distroless, and Chainguard images through a single service. This extended coverage eliminates the need for multiple scanning solutions while maintaining robust security practices across your entire container ecosystem, from traditional distributions to highly optimized container environments. The service streamlines security operations by providing comprehensive vulnerability management through a centralized platform, enabling efficient assessment of all container types.

Enhanced cross-account visibility – Security management across single accounts, cross-account setups, and AWS Organizations is now supported through delegated administrator capabilities. Amazon Inspector shares images running on container information within the same organization, which is particularly valuable for accounts maintaining golden image repositories. Amazon Inspector provides all ARNs for Amazon EKS and Amazon ECS clusters where images are running, if the resource belongs to the account with an API, providing comprehensive visibility across multiple AWS accounts. The system updates deployed EKS pods or ECS tasks information at least one time daily and automatically maintains accuracy as accounts join or leave the organization.

Availability and pricing – The new container mapping capabilities are available now in all AWS Regions where Amazon Inspector is offered at no additional cost. To get started, visit the AWS Inspector documentation. For pricing details and Regional availability, refer to the AWS Inspector pricing page.

PS: Writing a blog post at AWS is always a team effort, even when you see only one name under the post title. In this case, I want to thank Nirali Desai, for her generous help with technical guidance, and expertise, which made this overview possible and comprehensive.

— Eli


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

New Amazon EC2 P6-B200 instances powered by NVIDIA Blackwell GPUs to accelerate AI innovations

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/new-amazon-ec2-p6-b200-instances-powered-by-nvidia-blackwell-gpus-to-accelerate-ai-innovations/

Today, we’re announcing the general availability of Amazon Elastic Compute Cloud (Amazon EC2) P6-B200 instances powered by NVIDIA B200 to address customer needs for high performance and scalability in artificial intelligence (AI), machine learning (ML), and high performance computing (HPC) applications.

Amazon EC2 P6-B200 instances accelerate a broad range of GPU-enabled workloads but are especially well-suited for large-scale distributed AI training and inferencing for foundation models (FMs) with reinforcement learning (RL) and distillation, multimodal training and inference, and HPC applications such as climate modeling, drug discovery, seismic analysis, and insurance risk modeling.

When combined with Elastic Fabric Adapter (EFAv4) networking, hyperscale clustering by EC2 UltraClusters, and advanced virtualization and security capabilities by AWS Nitro System, you can train and serve FMs with increased speed, scale, and security. These instances also deliver up to two times the performance for AI training (time to train) and inference (tokens/sec) compared to EC2 P5en instances.

You can accelerate time-to-market for training FMs and deliver faster inference throughput, which lowers inference cost and helps increase adoption of generative AI applications as well as increased processing performance for HPC applications.

EC2 P6-B200 instances specifications
New EC2 P6-B200 instances provide eight NVIDIA B200 GPUs with 1440 GB of high bandwidth GPU memory, 5th Generation Intel Xeon Scalable processors (Emerald Rapids), 2 TiB of system memory, and 30 TB of local NVMe storage.

Here are the specs for EC2 P6-B200 instances:

Instance size GPUs (NVIDIA B200) GPU
memory (GB)
vCPUs GPU Peer to peer (GB/s) Instance storage (TB) Network bandwidth (Gbps) EBS bandwidth (Gbps)
P6-b200.48xlarge 8 1440 HBM3e 192 1800 8 x 3.84 NVMe SSD 8 x 400 100

These instances feature up to 125 percent improvement in GPU TFLOPs, 27 percent increase in GPU memory size, and 60 percent increase in GPU memory bandwidth compared to P5en instances.

P6-B200 instances in action
You can use P6-B200 instances in the US West (Oregon) AWS Region through EC2 Capacity Blocks for ML. To reserve your EC2 Capacity Blocks, choose Capacity Reservations on the Amazon EC2 console.

Select Purchase Capacity Blocks for ML and then choose your total capacity and specify how long you need the EC2 Capacity Block for p6-b200.48xlarge instances. The total number of days that you can reserve EC2 Capacity Blocks is 1-14 days, 21 days, 28 days, or multiples of 7 up to 182 days. You can choose your earliest start date for up to 8 weeks in advance.

Now, your EC2 Capacity Block will be scheduled successfully. The total price of an EC2 Capacity Block is charged up front, and the price doesn’t change after purchase. The payment will be billed to your account within 12 hours after you purchase the EC2 Capacity Blocks. To learn more, visit Capacity Blocks for ML in the Amazon EC2 User Guide.

When launching P6-B200 instances, you can use AWS Deep Learning AMIs (DLAMI) to support EC2 P6-B200 instances. DLAMI provides ML practitioners and researchers with the infrastructure and tools to quickly build scalable, secure, distributed ML applications in preconfigured environments.

To run instances, you can use AWS Management Console, AWS Command Line Interface (AWS CLI) or AWS SDKs.

You can integrate EC2 P6-B200 instances seamlessly with various AWS managed services such as Amazon Elastic Kubernetes Services (Amazon EKS), Amazon Simple Storage Service (Amazon S3), and Amazon FSx for Lustre. Support for Amazon SageMaker HyperPod is also coming soon.

Now available
Amazon EC2 P6-B200 instances are available today in the US West (Oregon) Region and can be purchased as EC2 Capacity blocks for ML.

Give Amazon EC2 P6-B200 instances a try in the Amazon EC2 console. To learn more, refer to the Amazon EC2 P6 instance page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

Channy


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Powering generative AI/ML solutions with AWS Outposts Servers at Edge locations

Post Syndicated from Art Baudo original https://aws.amazon.com/blogs/compute/powering-generative-ai-ml-solutions-with-aws-outposts-servers-at-edge-locations/

This post is written by Brian Daugherty, Principal Solutions Architect, Leonardo Queirolo, Senior Cloud Support Engineer, and Reet Kundu, Senior Cloud Support Engineer

Powering generative AI/ML solutions with AWS Outposts Servers at Edge locations

Many organizations are vigorously pursuing generative AI initiatives in the Amazon Web Services (AWS) cloud today because generative AI drive advances in productivity, efficiency, and innovation.

However, for some organizations, industries, and use-cases, there is a compelling need to deploy generative AI not only in the cloud, but also at the edge due to factors such as application latency and proximity to critical data.

AWS Outposts can help these organizations address this need by extending AWS services to the edge, such as generative AI services, while maintaining the same tooling and orchestration capabilities found in AWS Regions.

Industrial and manufacturing use-cases are a primary focus of AWS Outposts Servers, which can be deployed on-premises to minimize latency and make sure of stable connectivity between orchestration and control applications such as Manufacturing Execution Systems (MES) or Supervisory, Control, and Data Acquisition (SCADA) systems and the industrial processes they control.

This post explores how to use Outposts Servers to power generative AI solutions at the edge. The example use-case demonstrates real-time anomaly detection for industrial processes and an edge-based human machine interface including a small language model (SLM) with Retrieval-Augmented Generation (RAG) to guide operators on best practices for problem resolution. Although the use case is specific, the tools and methods can be applied to many other edge generative AI use cases.

For a hands-on experience to implement this solution using Outposts Servers, fill out this form with your contact information and we will get back to you with lab access. A detailed step-by-step guide to develop the hands-on example is available in this link.

Architecture overview

As depicted in the following diagram, the solution is distributed in three modules. The first module (1) guides you to establish low-latency, local connectivity to an MQTT broker within the same on-premises network as your lab Amazon Elastic Compute Cloud (Amazon EC2) instance. You configure essential AWS infrastructure (Amazon S3, AWS Secrets Manager, AWS Identity and Access Management (IAM)) to manage the deployment, authentication, and permissions of AWS IoT Greengrass components. You deploy a component to the existing Greengrass core device on your lab EC2 instance to retrieve synthetic Arduino sensor data from the broker using its Local Network Interface (LNI).
Figure 1 – Architectural diagram of the solution to perform low-latency, local inference through generative AI and ML models running on Outposts Servers

Figure 1 – Architectural diagram of the solution to perform low-latency, local inference through generative AI and ML models running on Outposts Servers

In the second module (2), you deploy a component that detects anomalies in sensor data in real-time. This component runs on the Outposts Server EC2 instance hosting the AWS IoT Greengrass core device, performing inference directly at the edge. You use synthetic Arduino sensor data to generate anomalies and observe them being detected by the model. You configure an IoT rule to send the anomaly count to the Amazon CloudWatch Dashboard in the Region. This provides centralized monitoring, while making sure that the raw data and any sensitive data remains processed locally at the edge where latency and connectivity are assured.

In the third module (3), you deploy a comprehensive edge computing solution to enhance operational visibility and decision-making capabilities at the local level. The solution includes a local dashboard that provides a real-time telemetry to display raw sensor data and detect anomalies. A Virtual Assistant is integrated with SLM to provide context-aware response from the factory data and forecasting capability to predict future anomaly trends.

Outposts Server

Outposts Servers provide fully managed AWS infrastructure, services, APIs, and tools for edge use-cases . Two form factors are available: 1U servers are AWS Graviton based, and 2U servers are third-generation Intel Xeon Scalable processor based.

Enabling anomaly detection at the edge

Outposts Servers allow local sensor data processing for low-latency anomaly detection and resilience against external connectivity issues, as shown in the following figure. The example uses synthetic Arduino devices with gyroscope sensors data, simulating industrial sensors sending data to an MQTT Broker on an EC2 instance in the Outposts Server. Gyroscope data is used in various monitoring systems, such as motion control systems, orientation detection, stability, and balance mechanism. The Lab EC2 instance fetches sensor data through the MQTT client and processes it using a machine learning (ML) model for anomaly detection.

Figure 2 – Architectural diagram showing data flow from Arduino sensors through MQTT broker and EC2 on Outposts Server to perform local inference

Figure 2 – Architectural diagram showing data flow from Arduino sensors through MQTT broker and EC2 on Outposts Server to perform local inference

Outposts server LNI

Local communication between synthetic Arduino sensor data, MQTT broker, and the Lab EC2 instance uses LNI, providing Layer 2 presence on the local network. The setup necessitates creating an Elastic Network Interface (ENI) on an Outposts subnet with the LNI enabled, attaching it to the Lab EC2 Instance, and verifying connectivity through the MQTT Broker’s LNI IP using the command ping -c 5 <MQTT_BROKER_LNI_IP> . This enables direct, low-latency communication between components crucial for this edge computing scenario.

AWS IoT Greengrass

AWS IoT Greengrass is an open source edge runtime and cloud service for device software management and deployment supported on Outposts Server. This hybrid approach combines the benefits of edge computing with centralized management, such as:

  • Centralized artifact management: store and version component artifacts in Amazon S3, enabling consistent deployment across multiple edge locations.
  • Secure configuration: use Secrets Manager to handle sensitive information and credentials unique to each edge location.
  • Fleet monitoring: use CloudWatch for centralized monitoring and logging across your distributed edge deployment.
  • Automated updates: deploy software updates and model improvements across your edge fleet through AWS IoT Greengrass component management.

AWS IoT Greengrass components, such as the one used for the anomaly detection, can be deployed to EC2 instances running on Outposts Servers. After configuring the Lab EC2 instance with Greengrass, you can download components from an S3 bucket. The first component deploys a subscriber for receiving synthetic Arduino sensor data through MQTT broker configuration, as shown in the following configuration line.

{
    "broker": "<MQTT_BROKER_LNI_IP>",
    "port": 1883,
    "client_id": "OutpostsServerMLEdge_<workshop-id>",
    "sensor_name": "ArduinoSensor_<arduino-id>",
    "topic": "arduino/ArduinoSensor_<arduino-id>/3-axis-rotation",
    "thing_name": "OutpostsServerMLEdge_Sub",
    "mqttauth_creds": "<ARN_SECRET_MQTT_CREDENTIALS>"
}

The second component is the Anomaly Detector artifact that processes sensor data in real-time, detects anomalies using a pre-trained model, and sends anomaly counts to AWS IoT Core. Key components include:

  • edge_application.py: script for processing sensor data, performing local inference using pre-trained model in ONNX format, and publishing anomaly counts to AWS IoT Core. It is used for local inference, so that the raw data is not exposed outside the Edge location.
  • model: directory storing “arduino.onnx”, a pre-trained Autoencoder model for anomaly detection.
  • statistics: directory storing the values of different statistical functions (for example, mean and standard deviation) from the training phase and used by edge_application.py for inference.
  • functions: directory storing the code of the functions, such as the code to publish to the AWS IoT Core.

After deployment of subscriber and detector components, the Lab EC2 instance processes synthetic gyroscope data from Arduino sensors, detecting anomalies during X, Y, or Z axis movement:

Real-time Dashboard showing sensor data and anomaly count

Real-time anomaly detection results from gyroscope sensor data across X, Y, and Z axes.

Building upon the foundation of Outposts Server, Local Network Interface (LNI), and AWS IoT Greengrass, this solution extends beyond anomaly detection to deliver comprehensive edge AI capabilities. These core components work together to enable advanced generative AI applications at the edge, as demonstrated in the following sections.

Edge generative AI applications with Outposts Server

The solution demonstrates the implementation of key edge generative AI capabilities:

  • Contextual virtual assistance: providing on-site personnel with AI-powered guidance and troubleshooting using local operational data, SOPs, and technical documentation.
  • Predictive insights: using foundational models (FMs) to forecast future trends based on historical data, enabling proactive planning and optimization.
  • Real-time operational dashboard: integrating sensor data visualization with AI-powered insights and forecasts in a unified local interface that maintains operations during connectivity interruptions.

1. Contextual virtual assistance at the edge

The solution implements the virtual assistant through an AWS IoT Greengrass component. The following is a snippet from the component recipe showing the key configuration parameters:

{
    "ComponentConfiguration": {
        "DefaultConfiguration": {
            // Workshop defaults, SLM runs locally on same EC2 instance
            "SLM_endpoint": "http://localhost:8080",  
            "embedding_model": "all-MiniLM-L6-v2",    
            "knowledge_base_directory": "Factory_Data" 
        }
    }
    // Additional component recipe configurations...
}

Although the solution demonstrates a streamlined setup with the SLM running on the same EC2 instance as the AWS IoT Greengrass component, the architecture enables flexible deployment options through the SLM_endpoint configuration. Organizations can:

  • Deploy the SLM on a dedicated resource in their on-premises network (for example "http://<LNI-IP-DEDICATED-RESOURCE>:8080")
  • Use existing hardware infrastructure accessible through LNI
  • Scale SLM compute resources independently from the AWS IoT Greengrass component
  • Maintain low-latency communication through local network interfaces

The implementation showcases a streamlined approach to RAG at the edge through three main components:

Knowledge base management: the solution uses Amazon S3 for document storage (PDFs, Markdown, text) with automatic edge deployment through AWS IoT Greengrass. Alternatively, you can also choose to store the documents in a local storage. A vector database, such as ChromaDB, handles local vector storage and similarity search, enabling efficient knowledge base updates with centralized control.

Flexible query processing: the implementation provides a streamlined interface for RAG management, allowing users to load site-specific knowledge bases and switch between basic SLM and RAG-enhanced responses with local context:

if prompt := st.chat_input("Question"):
if "db" in st.session_state:
        prompt = augmentPrompt(prompt, st.session_state["db"])
response = getStreamingAnswer(prompt, SLM_MODEL_ENDPOINT)

Modular SLM integration: The solution uses a standardized chat completion API, which allows for integration with different SLM deployments while maintaining a consistent interface across the edge fleet:

def getStreamingAnswer(question: str, endpoint: str):    
    chat_template = '<|user|>\n{input} <|end|>\n<|assistant|>'
    payload = {
        'messages': [{'content': f'{chat_template.format(input=question)}'}],
        'stream': True
    }
    SLM_URL = endpoint + '/v1/chat/completions'

This flexible architecture can be adapted for many industrial use-cases where latency and proximity to local data-sources and processes are critical.

2. Predictive insights using local models

The solution demonstrates forecasting capabilities using Chronos, a small and efficient time series forecasting model that can run entirely at the edge. The following solution implementation shows how to process historical data and generate predictions using Chronos on the AWS IoT Greengrass component deployed on Outposts Server:

# Load Chronos model locally on the Outposts Server
pipeline = ChronosPipeline.from_pretrained(
    "amazon/chronos-t5-small",
    device_map="cpu",
    torch_dtype=torch.bfloat16,
)
# Generate forecasts with confidence intervals
def predict_anomaly_count_data():
    forecast = pipeline.predict(
        context = torch.tensor(df["total_anomalies"]),
        prediction_length = pred_length,
        num_samples = n_samples,
        top_k = 50,
        top_p = 1.0,
    )
    
    # Calculate confidence bounds
    low, median, high = np.quantile(forecast[0].numpy(), [0.1, 0.5, 0.9], axis=0)

Although the solution uses sample data for the demonstration, this architecture allows organizations to process complex, real-time data at each edge location. Companies can choose to upload only aggregated metrics to CloudWatch or Amazon QuickSight for fleet monitoring and BI analysis, making sure that sensitive raw data remains secure at the edge.

3. Real-time operational dashboard

The solution showcases a resilient monitoring solution where all inter-component communication occurs within the local network and processing happens on the Outposts server, making sure of full functionality during external network interruptions. The dashboard is accessible through the LNI of the Outposts server, allowing local clients to maintain access through the LNI IP address even when connectivity to the Region is lost.

Through a unified interface, the dashboard provides:

  • Real-time visualization of sensor readings
  • Anomaly detection results from the local ML component
  • AI-powered insights from the local SLM
  • Trend forecasting from the Chronos model

Real-time Dashboard showing sensor data and anomaly count

Real-time Dashboard showing sensor data and anomaly count

Virtual Assistant leveraging Factory Data to provide contextualized answers

Virtual Assistant leveraging Factory Data to provide contextualized answers

Chronos forecasting anomaly count based on historical data

Chronos forecasting anomaly count based on historical data

Conclusion

The implementation demonstrates how AWS Outposts Server enables organizations to use both traditional ML and advanced generative AI capabilities at the edge for a variety of industrial and manufacturing use-cases where low-latency and proximity to sensitive or real-time data are business- and process-critical.

To get started with AWS Outposts and explore use cases like this edge AI solution, fill out this form and our team will contact you with lab access and additional guidance. For a detailed walkthrough of this specific edge AI example, refer to this step-by-step guide. For more information about AWS Outposts Server, see the AWS Outposts Server User Guide.

Anchoring AWS Outposts servers with AWS Direct Connect

Post Syndicated from Art Baudo original https://aws.amazon.com/blogs/compute/anchoring-aws-outposts-servers-with-aws-direct-connect/

This post is written by Perry Wald, Principal GTM SA, Hybrid Edge, Eric Vasquez Senior SA Hybrid Edge, and Fernando Galves Gen AI Solutions Architect, Outposts

AWS Outposts is a fully managed service that extends AWS infrastructure, services, APIs, and tools to customer premises. Outposts servers launched in 2022, a 1U or 2U rack-mountable host, with the ability to run Amazon Elastic Compute Cloud (Amazon EC2) and Amazon Elastic Container Service (Amazon ECS), as well as other appropriate smaller scale edge services such as AWS IoT Greengrass. This version of Outposts is primarily focused on bringing lower latency, AWS compute capabilities to the edge at many user locations.

During Outposts provisioning, you or AWS creates a service link connection that connects your Outposts server to your chosen AWS Region or home Region. Outposts depends on regional connectivity “to reach out to home,” needing very little in terms of networking. Looking at the network requirements, it needs:

  • DHCP, to assign an IP address and a default gateway
  • Public DNS, to resolve the name of the initial regional endpoint, to allow automated setup, and
  • Internet access, so that when the regional endpoint has been resolved, the Outpost can reach that endpoint. With a minimum of 500 Mbps or and a max of 175 ms round trip latency

User challenges with internet connectivity at the edge

When you order an Outposts server, you are responsible for installing the server. Outposts servers are self-provisioning and need a service link connection between your Outposts and the AWS Region (or home Region). This connection allows for the management of Outposts and the exchange of traffic to and from the AWS Region. Server deployment can be broken down into the following steps: installing the Outposts servers, powering them on, and providing authentication details through a command line. Then, the Outpost servers reach out to the regional endpoint, and provision themselves. Your Outpost status will show as Active when the process has completed, it could take a few hours depending on service link bandwidth.

Although this has been suitable for the vast majority of use cases, there are some locations that can’t provide internet connectivity in their environments. This has mostly been in use cases where there is a strong security reason for not having an internet connection (such as financial services kiosks, small manufacturing facilities, and defense), so as to avoid risks such as DDoS attacks and potential hack attempts, or to meet requirements for receiving an authority to operate (ATO).

These locations either have some form of direct connect, or more commonly have a centralized direct connect link to AWS, and an MPLS network linking all their remote sites to a central one. In both of these scenarios, the requirement is to allow the Outpost servers to resolve and reach the public endpoint for setup, and subsequently the public anchor endpoint for management. This is done without needing to leave the AWS ecosystem, without needing to expose themselves unnecessarily to potential internet threats, and without adding more systems to manage themselves, but rather making use of AWS services.

To meet this requirement, we identified several key things that need to be provided if the user does not have internet connectivity at the remote location, as follows:

  1. DHCP, to provide the Outposts servers with an IP address, default gateway, and DNS servers.
  2. Public DNS access to resolve both the setup endpoint, and when live, the anchor endpoint.
  3. Public internet access, without exposing the user location to potentially harmful traffic from the internet.

Direct Connect VIF options

There are three different types of Virtual Interfaces (VIF) possible to configure on an AWS Direct Connect link:

  • Public VIF: A public VIF can access all AWS public services using public IP addresses.
  • Private VIF: A private VIF should be used to access an Amazon Virtual Private Cloud (Amazon VPC) using private IP addresses.
  • Transit VIF: A transit VIF should be used to access one or more Amazon VPC Transit Gateways associated with Direct Connect gateways.

Transit VIF option

A transit VIF can be used to solve both of these issues. First, a transit VIF deploys an ENI within a VPC (known as an attachment), so that traffic coming from the transit VIF into a VPC can be routed. This is because it follows the rule that, for non-transitive VPC routing, the traffic has to either be sourced or targeted for an ENI in the VPC.

If the traffic is forwarded to a regional VPC through the transit gateway, then it can be forwarded to the internet through an NAT gateway. This is an enhancement of the architecture to use a transit gateway to provide a single egress point for multiple VPCs to the internet. For more information, see Creating a single internet exit point from multiple VPCs Using AWS Transit Gateway. In this case, instead of the transit gateway routing multiple VPCs to the internet, it’s routing to an on-premises connection.

Using a transit gateway to forward traffic to an NAT gateway allows you to provide internet connectivity for the Outposts servers without managing virtual appliances, because NAT gateway provides this as a service. NAT gateways also only allow outbound access, so they provide security against any attempted external access by a bad actor from the internet. This works for Outposts servers since they only need outbound access. Outposts always initiate communication to an anchor or service endpoint, and they never receive communication except as a response.

Architectural diagram showing the use of a Transit VIF and NAT gateway in a Region reaching regional endpoints

Figure 1. Architectural diagram showing the use of a Transit VIF and NAT gateway in a Region reaching regional endpoints

DNS provisioning

Although the preceding architecture solves the challenge of how we provide a path for IP packets to transit between the Outposts servers and the public endpoints needed, it doesn’t solve the issue of resolving DNS names. If the remote site is isolated from the internet, then it has no clear way to resolve DNS.

Amazon Route53 resolver endpoints allow you to deploy an IP address within a VPC subnet, which provides DNS resolution. There are two types of resolver endpoints: outbound and inbound.

Outbound resolver endpoints are used by AWS to send DNS queries to your on-premises DNS servers. Inbound resolver endpoints are used by your DNS servers (and hosts) to resolve addresses within Route 53.

Route 53 can resolve public DNS names, so the Outposts service endpoint outposts.<region-name>.amazonaws.com becomes resolvable by an inbound resolver endpoint.

Configuring the Outposts egress VPC

  1. Set up service link egress VPC, build subnets, deploy a NAT gateway, and transit gateway.
  2. Create Route 53 resolver inbound endpoint.
  3. Configure DHCP on the switch, and make sure that the DNS value matches resolver endpoint.
  4. Configure Transit VIF on the switch, build a BGP peer, and attach to your transit gateway.
  5. Confirm propagation settings on transit gateway and default routes.
  6. Confirm routes on subnets to allow traffic out to the internet, and back to your Outpost servers.
  7. Test name resolution (dig) and https (curl) test to service endpoint.
  8. If needed, install your Outpost servers.

Public VIF option

Using a public VIF allows you to provide an internet connection directly to the on-premises site. In turn, this means you need to implement firewalls and security functions on this connection, adding more layers of operational overhead. A public VIF also means that the on-premises end of the VIF can be accessed by any public IP on the AWS public network, regardless of the instance to which IP is mapped. A public VIF is a public IP endpoint on the AWS public network. You should treat public VIF traffic as internet-based traffic. This can become cumbersome for firewalls teams if they have to allow-list known AWS IP ranges and manage the stateful firewall for a long range of AWS IPs.

Furthermore, even if the user is happy to implement and manage a firewall on the end of that public VIF, there is still a question of how the Outpost would resolve DNS in this setup, and subsequent anchor endpoints. Unless the private network already has DNS resolution to a public DNS, then there are no DNS servers that DHCP can point to in order to allow the Outposts servers to get name resolution. This is because there is no public DNS endpoint within the AWS public network. Traffic from a user’s public VIF can access the AWS public network, but it can’t exit it to other public networks. For example, if the you had configured DHCP to point to one of the well-known DNS servers (such as 8.8.8.8), then, since this DNS servers lives outside of the AWS public network, requests originating from the on-premises side of a public VIF would be dropped as it hit the border of the AWS autonomous system.

The only way for a DNS request to be resolved would be to build a bind forwarding service within a VPC, provide it with a public IP address, and point the DHCP DNS values at this IP address.

This network configuration introduces complexity, and won’t be possible for those with highly regulated workloads. You would need to manage a firewall on-premises, allow a public network to reach the on-premises location, and manage a bind servers setup within a VPC. For these reasons, a public VIF is generally not an option unless the user is already running one, and is familiar with the steps to secure it.

Figure 2. Architectural diagram showing traffic flow using a public VIF and AWS Outposts

Private VIF option

A private VIF whether connected directly to a virtual private gateway (VGW), or through a Direct Connect gateway. VPCs do not support transitive routing. To explain this another way, any traffic following a routing rule in a subnet route table has to either originate from, or be destined for, an IP address (or to be more explicit, an Elastic Network Interface (ENI)) inside that VPC.

Virtual private gateways do not have an ENI associated with them, but are pointed to as a next hop within a subnet routing table. If we take this example and look at what the Outposts servers would be trying to pass as traffic, then it would send a packet with a source address of the Outposts servers, and a destination address of the Outposts service public endpoint (assuming that it could resolve it). When this packet reaches the VPC, then neither the source nor destination address would belong to an ENI within the VPC. Therefore, VPC routing would drop the packet.

Even if there was a routing rule on the subnet pointing the next hop for all traffic to a NAT gateway (ideal for internet egress), the routing still wouldn’t work. This is because the packet from the Outposts servers doesn’t have a destination of the NAT gateway, but instead a destination of the setup endpoint in the internet.

It’s possible to use a combination of ingress routing and transparent proxies to ingest the traffic and pass it to an instance running a proxy service to forward to the internet. However, this adds complexity having to manage and maintain proxy servers. For these reasons, a private VIF is generally not recommended.

Architectural diagram showing VGW and packet drops because of transitive routing not being supported

Figure 3. Architectural diagram showing VGW and packet drops because of transitive routing not being supported

Conclusion

In this post, we discussed architecture patterns you can use to provision your Outposts when public internet connectivity is unavailable. To get started with Outpost servers please visit our Server User Guide. For more information, contact us to learn more.