Tag Archives: Amazon Simple Storage Service (S3)

Using Amazon S3 Tables with Amazon Redshift to query Apache Iceberg tables

Post Syndicated from Jonathan Katz original https://aws.amazon.com/blogs/big-data/using-amazon-s3-tables-with-amazon-redshift-to-query-apache-iceberg-tables/

Amazon Redshift supports querying data stored using Apache Iceberg tables, an open table format that simplifies management of tabular data residing in data lakes on Amazon Simple Storage Service (Amazon S3). Amazon S3 Tables delivers the first cloud object store with built-in Iceberg support and streamlines storing tabular data at scale, including continual table optimizations that help improve query performance. Amazon SageMaker Lakehouse unifies your data across S3 data lakes, including S3 Tables, and Amazon Redshift data warehouses, helps you build powerful analytics and artificial intelligence and machine learning (AI/ML) applications on a single copy of data, querying data stored in S3 Tables without the need for complex extract, transform, and load (ETL) or data movement processes. You can take advantage of the scalability of S3 Tables to store and manage large volumes of data, optimize costs by avoiding additional data movement steps, and simplify data management through centralized fine-grained access control from SageMaker Lakehouse.

In this post, we demonstrate how to get started with S3 Tables and Amazon Redshift Serverless for querying data in Iceberg tables. We show how to set up S3 Tables, load data, register them in the unified data lake catalog, set up basic access controls in SageMaker Lakehouse through AWS Lake Formation, and query the data using Amazon Redshift.

Note – Amazon Redshift is just one option for querying data stored in S3 Tables. You can learn more about S3 Tables and additional ways to query and analyze data on the S3 Tables product page.

Solution overview

In this solution, we show how to query Iceberg tables managed in S3 Tables using Amazon Redshift. Specifically, we load a dataset into S3 Tables, link the data in S3 Tables to a Redshift Serverless workgroup with appropriate permissions, and finally run queries to analyze our dataset for trends and insights. The following diagram illustrates this workflow.

In this post, we will walk through the following steps:

  1. Create a table bucket in S3 Tables and integrate with other AWS analytics services.
  2. Set up permissions and create Iceberg tables with SageMaker Lakehouse using Lake Formation.
  3. Load data with Amazon Athena. There are different ways to ingest data into S3 Tables, but for this post, we show how we can quickly get started with Athena.
  4. Use Amazon Redshift to query your Iceberg tables stored in S3 Tables through the auto mounted catalog.

Prerequisites

The examples in this post require you to use the following AWS services and features:

Create a table bucket in S3 Tables

Before you can use Amazon Redshift to query the data in S3 Tables, you must first create a table bucket. Complete the following steps:

  1. In the Amazon S3 console, choose Table buckets on the left navigation pane.
  2. In the Integration with AWS analytics services section, choose Enable integration if you haven’t previously set this up.

This sets up the integration with AWS analytics services, including Amazon Redshift, Amazon EMR, and Athena.

After a few seconds, the status will change to Enabled.

  1. Choose Create table bucket.
  2. Enter a bucket name. For this example, we use the bucket name redshifticeberg.
  3. Choose Create table bucket.

After the S3 table bucket is created, you will be redirected to the table buckets list.

Now that your table bucket is created, the next step is to configure the unified catalog in SageMaker Lakehouse through the Lake Formation console. This will make the table bucket in S3 Tables available to Amazon Redshift for querying Iceberg tables.

Publishing Iceberg tables in S3 Tables to SageMaker Lakehouse

Before you can query Iceberg tables in S3 Tables with Amazon Redshift, you must first make the table bucket available in the unified catalog in SageMaker Lakehouse. You can do this through the Lake Formation console, which lets you publish catalogs and manage tables through the catalogs feature, and assign permissions to users. The following steps show you how to set up Lake Formation so you can use Amazon Redshift to query Iceberg tables in your table bucket:

  1. If you’ve never visited the Lake Formation console before, you must first do so as an AWS user with admin permissions to activate Lake Formation.

You will be redirected to the Catalogs page on the Lake Formation console. You will see that one of the catalogs available is the s3tablescatalog, which maintains a catalog of the table buckets you’ve created. The following steps will configure Lake Formation to make data in the s3tablescatalog catalog available to Amazon Redshift.

Next, you need to create a database in Lake Formation. The Lake Formation database maps to a Redshift schema.

  1. Choose Databases under Data Catalog in the navigation pane.
  2. On the Create menu, choose Database.

  1. Enter a name for this database. This example uses icebergsons3.
  2. For Catalog, choose the table bucket that you created. In this example, the name will have the format <ACCOUNT ID>:s3tablescatalog/redshifticeberg.
  3. Choose Create database.

You will be redirected on the Lake Formation console to a page with more information about your new database. Now you can create an Iceberg table in S3 Tables.

  1. On the database details page, on the View menu, choose Tables.

This will open up a new browser window with the table editor for this database.

  1. After the table view loads, choose Create table to start creating the table.

  1. In the editor, enter the name of the table. We call this table examples.
  2. Choose the catalog (<ACCOUNT ID>:s3tablescatalog/redshifticeberg) and database (icebergsons3).

Next, add columns to your table.

  1. In the Schema section, choose Add column, and add a column that represents an ID.

  1. Repeat this step and add columns for additional data:
    1. category_id (long)
    2. insert_date (date)
    3. data (string)

The final schema looks like the following screenshot.

  1. Choose Submit to create the table.

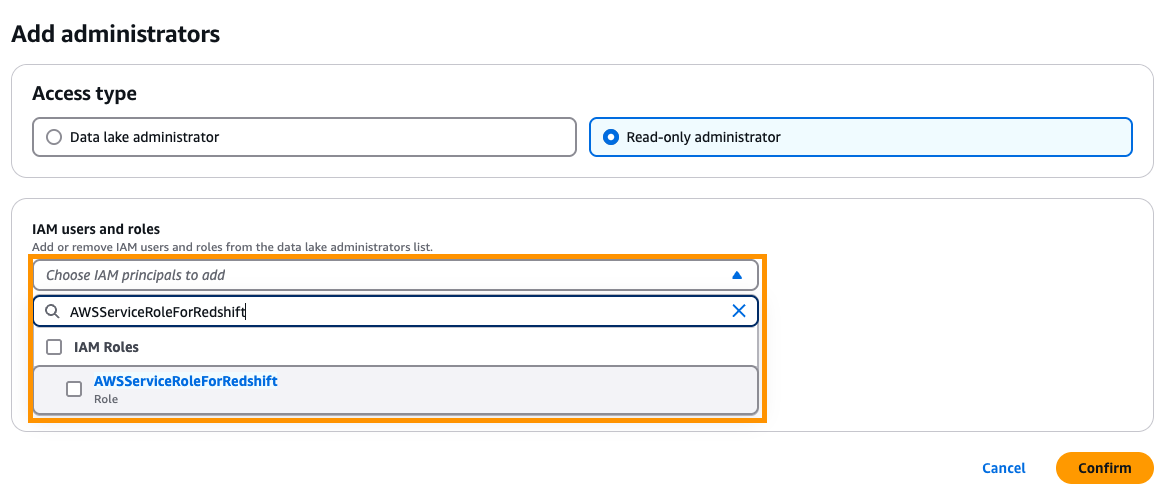
Next, you need to set up a read-only permission so you can query Iceberg data in S3 Tables using the Amazon Redshift Query Editor v2. For more information, see Prerequisites for managing Amazon Redshift namespaces in the AWS Glue Data Catalog.

  1. Under Administration in the navigation pane, choose Administrative roles and tasks.
  2. In the Data lake administrators section, choose Add.

  1. For Access type, select Read-only administrator.
  2. For IAM users and roles, enter AWSServiceRoleForRedshift.

AWSServiceRoleForRedshift is a service-linked role that’s managed by AWS.

  1. Choose Confirm.

You have now configured SageMaker Lakehouse using Lake Formation to allow Amazon Redshift to query Iceberg tables in S3 Tables. Next, you populate some data into the Iceberg table, and query it with Amazon Redshift.

Use SQL to query Iceberg data with Amazon Redshift

For this example, we use Athena to load data into our Iceberg table. This is one option for ingesting data into an Iceberg table; see Using Amazon S3 Tables with AWS analytics services for other options, including Amazon EMR with Spark, Amazon Data Firehose, and AWS Glue ETL.

  1. On the Athena console, navigate to the query editor.
  2. If this is your first time using Athena, you must first specify a query result location before executing your first query.
  3. In the query editor, under Data, choose your data source (AwsDataCatalog).
  4. For Catalog, choose the table bucket you created (s3tablescatalog/redshifticeberg).
  5. For Database, choose the database you created (icebergsons3).

  1. Let’s execute a query to generate data for the examples table. The following query generates over 1.5 million rows corresponding to 30 days of data. Enter the query and choose Run.
INSERT INTO icebergsons3.examples
SELECT
    b.id * (date_diff('day', CURRENT_DATE, a.insert_date) + 1),
    b.id % 1000, a.insert_date,
    CAST(random() AS varchar)
FROM
    unnest(
        sequence(CURRENT_DATE, CURRENT_DATE + INTERVAL '30' DAY, INTERVAL '1' DAY)
    ) AS a(insert_date),
    unnest(sequence(1, 50000)) AS b(id);

The following screenshot shows our query.

The query takes about 10 seconds to execute.

Now you can use Redshift Serverless to query the data.

  1. On the Redshift Serverless console, provision a Redshift Serverless workgroup if you haven’t already done so. For instructions, see Get started with Amazon Redshift Serverless data warehouses guide. In this example, we use a Redshift Serverless workgroup called iceberg.
  2. Make sure that your Amazon Redshift patch version is patch 188 or higher.

  1. Choose Query data to open the Amazon Redshift Query Editor v2.

  1. In the query editor, choose the workgroup you want to use.

A pop-up window will appear, prompting what user to use.

  1. Select Federated user, which will use your current account, and choose Create connection.

It will take a few seconds to start the connection. When you’re connected, you will see a list of available databases.

  1. Choose External databases.

You will see the table bucket from S3 Tables in the view (in this example, this is redshifticeberg@s3tablescatalog).

  1. If you continue clicking through the tree, you will see the examples table, which is the Iceberg table you previously created that’s stored in the table bucket.

You can now use Amazon Redshift to query the Iceberg table in S3 Tables.

Before you execute the query, review the Amazon Redshift syntax for querying catalogs registered in SageMaker Lakehouse. Amazon Redshift uses the following syntax to reference a table: [email protected] or database@namespace".schema.table.

In this example, we use the following syntax to query the examples table in the table bucket: r[email protected].

Learn more about this mapping in Using Amazon S3 Tables with AWS analytics services.

Let’s run some queries. First, let’s see how many rows are in the examples table.

  1. Run the following query in the query editor:
SELECT count(*)
FROM [email protected]; 

The query will take a few seconds to execute. You will see the following result.

Let’s try a slightly more complicated query. In this case, we want to find all the days that had example data starting with 0.2 and a category_id between 50–75 with at least 130 rows. We will order the results from most to least.

  1. Run the following query:
SELECT examples.insert_date, count(*)
FROM [email protected]
WHERE
    examples.data LIKE '0.2%' AND
    examples.category_id BETWEEN 50 AND 75
GROUP BY examples.insert_date
HAVING count(*) > 130
ORDER BY count DESC;

You might see different results than the following screenshot due the randomly generated source data.

Congratulations, you have set up and queried Iceberg data in S3 Tables from Amazon Redshift!

Clean up

If you implemented the example and want to remove the resources, complete the following steps:

  1. If you no longer need your Redshift Serverless workgroup, delete the workgroup.
  2. If you don’t need to access your SageMaker Lakehouse data from the Amazon Redshift Query Editor v2, remove the data lake administrator:
    1. On the Lake Formation console, choose Administrative roles and tasks in the navigation pane.
    2. Remove the read-only data lake administrator that has the AWSServiceRoleForRedshift privilege.
  3. If you want to permanently delete the data from this post, delete the database:
    1. On the Lake Formation console, choose Databases in the navigation pane.
    2. Delete the icebergsahead database.
  4. If you no longer need the table bucket, delete the table bucket.
  5. In you want to deactivate the integration between S3 Tables and AWS analytics services, see Migrating to the updated integration process.

Conclusion

In this post, we showed how to get started with Amazon Redshift to query Iceberg tables stored in S3 Tables. This is just the beginning for how you can use Amazon Redshift to analyze your Iceberg data that’s stored in S3 Tables—you can combine this with other Amazon Redshift features, including writing queries that join data from Iceberg tables stored in S3 Tables and Redshift Managed Storage (RMS), or implement data access controls that give you fine-granted access control rules for different users across the S3 Tables. Additionally, you can use features like Redshift Serverless to automatically select the amount of compute for analyzing your Iceberg tables, and use AI to intelligently scale on demand and optimize query performance characteristics for your analytical workload.

We invite you to leave feedback in the comments.


About the Authors

Jonathan Katz is a Principal Product Manager – Technical on the Amazon Redshift team and is based in New York. He is a Core Team member of the open source PostgreSQL project and an active open source contributor, including PostgreSQL and the pgvector project.

Satesh Sonti is a Sr. Analytics Specialist Solutions Architect based out of Atlanta, specialized in building enterprise data platforms, data warehousing, and analytics solutions. He has over 19 years of experience in building data assets and leading complex data platform programs for banking and insurance clients across the globe.

Optimizing network footprint in serverless applications

Post Syndicated from Chris McPeek original https://aws.amazon.com/blogs/compute/optimizing-network-footprint-in-serverless-applications/

This post is authored by Anton Aleksandrov, Principal Solution Architect, AWS Serverless and Daniel Abib, Senior Specialist Solutions Architect, AWS

Serverless application developers may commonly encounter scenarios where they need to transport large payloads, especially when building modern cloud applications that need rich data. Examples include analytics services with detailed reports, e-commerce platforms with extensive product catalogs, healthcare applications transmitting patient records, or financial services aggregating transactional data.

Many serverless services have a well-defined maximum payload size. For example, AWS Lambda maximum request/response payload size is 6 MB, and Amazon Simple Queue Service (Amazon SQS) and Amazon EventBridge maximum message size is 256 KB. In this post, you will learn how to use data compression techniques to reduce your network footprint and transport larger payloads under existing constraints.

Overview

Cloud applications evolve continuously and need to be adjusted frequently for new requirements, such as new business features or new Service Level Objectives (SLO) for higher throughput and lower latency. As new use cases and data patterns are added, it is common to see request and response payload sizes increase. At some point, you might hit the maximum service payload size limits, such as 6 MB for synchronous Lambda function invokes, 10 MB for Amazon API Gateway, and 256 KB for Amazon SQS, EventBridge, and asynchronous Lambda invokes.

There are several techniques you can apply when dealing with large payloads. If your payloads are tens of MBs or more, or you need to transport large binary objects with API Gateway, you can store the payload on Amazon Simple Storage Service (Amazon S3) and use pre-signed URLs for clients to directly upload and download from S3.

A sample of architecture for handling large payloads.

Figure 1. A sample of architecture for handling large payloads

Lambda function URLs response streaming supports up to 20 MB responses. For handling large messages with services such as SQS or EventBridge, you can store the message in S3 and pass a reference. The downstream consumer will use the reference to download the message directly from S3. One common characteristic of these techniques is that they introduce architectural complexity and may necessitate modifications to your existing solution architecture and data flow patterns.

Furthermore, as your payloads grow in size, you will see increased data transfer costs, especially if your solution is transporting data through Amazon Virtual Private Cloud (VPC) NAT Gateways, VPC endpoints, or sending data across AWS Regions. For example, it is common for VPC-based solutions to have Lambda functions in their architecture. A container running on Amazon Elastic Kubernetes Service (Amazon EKS) might need to invoke a Lambda function, or a VPC-attached Lambda function might need to reach out to the public internet.

Examples of using virtual network appliances with serverless applications.

Figure 2. Examples of using virtual network appliances with serverless applications

Both NAT Gateway and VPC Endpoint are billed per GB of data processed, which makes data compression a valuable optimization technique. Go to NAT Gateway pricing and VPC Endpoint pricing for details.

The following sections explore data compression techniques and demonstrate how to apply them in your serverless applications. You can learn how to send larger payloads within the existing payload size boundaries and reduce your network footprint without significant architectural changes. This post discusses compression techniques in the context of Lambda and API Gateway, but the same principles can be applied to other services, such as SQS, EventBridge, and AWS AppSync. Understanding compression concepts better equips you to optimize your application’s data-handling capabilities.

What is data compression?

Compression is a widely used approach to reduce data size in order to improve cost-effectiveness and performance for data storage and transmission. Many tools and frameworks incorporate data compression techniques, such as gzip or zstd. It is thoroughly documented in the official IANA specification and IETF RFC 9110. Browsers such as Chrome and Firefox, HTTP toolkits such as curl and Postman, and runtimes such as Node.js and Python natively handle compression, often without user involvement.

Consider HTTP protocol. When a client wants to send a compressed payload, it specifies it in the Content-Type header. To receive a compressed response, the client specifies supported compression methods in the Accept-Encoding request header.

Accept-Encoding request header specifying supported compression methods.

Figure 3. Accept-Encoding request header specifying supported compression methods

The server compresses the response payload using one of the supported methods and uses the Content-Encoding response header to indicate the method to the client.

Content-Encoding response header specifying compression method.

Figure 4. Content-Encoding response header specifying compression method

This mechanism can accelerate client-server communications by reducing the number of bytes transmitted over the network. Compression efficiency depends on the data type. Text-based formats like JSON, XML, HTML, and YAML compress well, while binary data such as PDF and JPEG generally compress less effectively.

Data compression with API Gateway

API Gateway provides built-in compression support. Use the minimumCompressionSize configuration to set the smallest payload size to compress automatically. The value can be between 0 bytes to 10 MB. Compressing very small payloads might actually increase the final payload size, and you should always test with your real payload patterns to determine the optimal threshold.

Handling data compression in API Gateway.

Figure 5. Handling data compression in API Gateway

API Gateway enables clients to interact with your API using compressed payloads through supported content encodings. The compression mechanism works bi-directionally. For JSON payloads, API Gateway seamlessly handles compression and decompression, maintaining compatibility with mapping templates. It decompresses incoming payloads before applying request mapping templates and compresses outgoing responses after applying response mapping templates. This automated compression optimizes data transfer:

  • When sending compressed data, clients supply the appropriate Content-Encoding header. API Gateway handles the decompression and applies configured mapping templates before forwarding the request to the integration.
  • When API Gateway receives an integration response and compression is enabled, it compresses the response payload and returns it to the client, provided that the client has included a matching Accept-Encoding header.

A sample test using the compression technique with API Gateway and JSON payload yielded the following results.

  • Compression disabled. Response size = 1 MB, response latency = 660 ms
  • Compression enabled. Response size = 220 KB, response latency = 550 ms

Compressing data resulted in 78% network footprint reduction and improved latency by 110 ms.

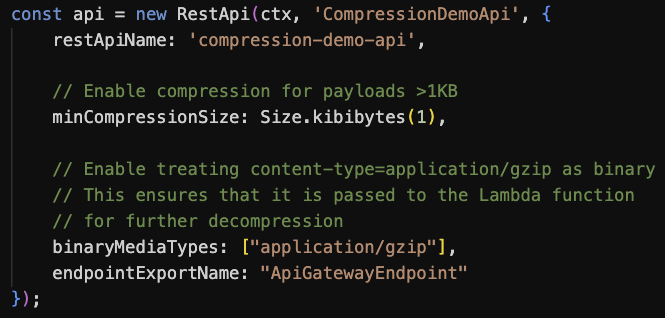
This configuration-based technique uses the API Gateway native compression. However, payloads are decompressed before being delivered to downstream integrations, thus they still remain subject to Lambda’s 6 MB max payload size. To address this, you can configure binaryMediaTypes in the API Gateway to pass compressed payloads to Lambda directly, enabling the function to handle decompression.

CDK code to configure API Gateway for data compression and binary data passthrough.

Figure 6. CDK code to configure API Gateway for data compression and binary data passthrough

Handling compressed data in Lambda functions

The Lambda Invoke API supports payloads in plain-text formats, such as JSON. The maximum payload size is 6 MB for synchronous invocations and 256 KB for asynchronous. Although the Invoke API supports uncompressed text-based payloads, you can introduce data compression in your function code and use API Gateway or Function URLs to facilitate content conversion, as illustrated in the following figure.

Transporting compressed payloads in a serverless applications.

Figure 7. Transporting compressed payloads in a serverless applications

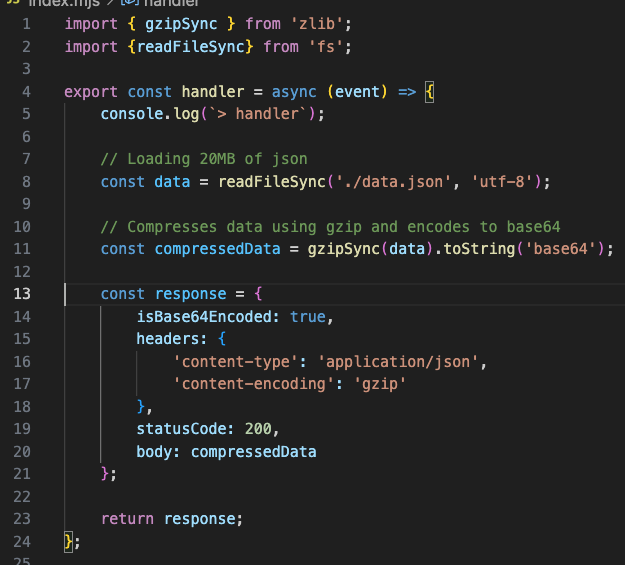
Handling data compression in your Lambda function code can be done through libraries commonly embedded in the runtime. The following code snippet shows the compressing response payload using Node.js. Similar techniques can be applied to other runtimes.

Sample code implementing response payload compression in a Lambda function.

Figure 8. Sample code implementing response payload compression in a Lambda function

  • Line 1: Import gzip functionality from the zlib module.
  • Lines 11: Compress and Base64-encode data. Gzip compression, similar to many other compression methods, produces a binary stream. Base64 encoding converts it to the text-based format expected by the Lambda service
  • Lines 13-21: Response object is created with isBase64Encoded=true and response headers telling the client that the response is a gzip-encoded JSON object.

The following screenshot shows the result: 20 MB uncompressed JSON returned from a Lambda function as a 2.5 MB compressed response body. Network footprint reduced by over 80%.

A screenshot from Postman showing the original and compressed payload size.

Figure 9. A screenshot from Postman showing the original and compressed payload size

Using this technique, you can reduce your network footprint and transport payload sizes several times higher than the Lambda maximum payload size.

Using Function URLs with compressed payloads

Transporting compressed payloads through Lambda Function URLs doesn’t necessitate any extra configuration. For handler responses, your code needs to compress and Base64-encode the data as shown in the preceding figure. For invocation requests, the Function URL endpoint recognizes the incoming compressed payload as binary and passes it to your handler as a Base64 encoded string in the event body.

Sample code implementing request payload decompression in a Lambda function.

Figure 10. Sample code implementing request payload decompression in a Lambda function

Trade-offs and testing results

Compressing data in function code is a CPU-intensive activity, potentially increasing invocation duration and, as a result, function cost. This, however, can be balanced by the benefits of data compression. As you’ve seen in previous sections, while compressing data adds compute latency, transporting smaller payloads over the network reduces network latency. The following section summarizes a series of tests performed to estimate the impact of data compression on Lambda function invocation duration, Lambda function invocation cost, and data transfer savings with both NAT Gateway and VPC Endpoint. The tests were performed with several assumptions and randomly generated JSON data. You can see full testing results in the sample GitHub.com repo.

Test results demonstrated that the impact on function latency and cost primarily depends on two key factors: payload size and allocated memory (which determines vCPU capacity). Using a Node.js runtime with ARM architecture as an example, compressing a 1 MB JSON object in a function with 1 GB of allocated memory resulted in 124 ms of added processing time on average. For 10 million invocations, this extra processing time adds approximately $16. At the same time, the compression yielded a 70% reduction in payload size. With the same number of invocations, this translates to approximately $300 in savings when using NAT Gateway and $70 in savings when using VPC Endpoints (depending on the number of Availability Zones (AZs)).

AWS Service pricing is updated regularly, you should always consult the respective pricing pages for the latest information. Moreover, you should conduct your own performance and cost estimates using payloads that represent your workloads. Compression effectiveness varies significantly depending on the data type: payloads with low compression rates might not benefit from this technique.

Sample application

Follow the instructions in this GitHub repository to provision the sample in your AWS account. The project creates two Lambda functions to demonstrate receiving and returning compressed JSON using Function URLs and API Gateway.

The sample shows how to GET and POST JSON payloads using gzip compression to reduce the network footprint by over 80%.

A screenshot from Postman showing the original and compressed payload size.

Figure 11. A screenshot from Postman showing the original and compressed payload size

Conclusion

Data compression enables larger payload transfers and reduces network footprint. It can help to lower network latencies and optimize data transfer costs. When implementing compression within Lambda functions, it is important to consider its CPU-bound nature, which may increase function duration and costs. You should always evaluate the added compute cost against potential data transfer savings to make sure the technique benefits your use case.

Compression is most effective for handling large text-based payloads and when a slight increase in compute latency balanced by reduced network latency is acceptable.

To learn more about Serverless architectures and asynchronous Lambda invocation patterns, see Serverless Land.

AWS Weekly Roundup: AWS Pi Day, Amazon Bedrock multi-agent collaboration, Amazon SageMaker Unified Studio, Amazon S3 Tables, and more

Post Syndicated from Prasad Rao original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-aws-pi-day-amazon-bedrock-multi-agent-collaboration-amazon-sagemaker-unified-studio-amazon-s3-tables-and-more/

Thanks to everyone who joined us for the fifth annual AWS Pi Day on March 14. Since its inception in 2021, commemorating the Amazon Simple Storage Service (Amazon S3) 15th anniversary, AWS Pi Day has grown into a flagship event highlighting the transformative power of cloud technologies in data management, analytics, and AI.

This year’s virtual event featured in-depth discussions with Amazon Web Services (AWS) product teams showcasing our continued innovation in helping customers build robust data foundations for analytics and AI workloads.

Missed the live event? You can still access all content on-demand at the event page. Whether you’re developing data lakehouses, training AI models, creating generative AI applications, or optimizing analytics workloads, the shared insights will help you maximize the value of your data.

Last week’s launches
Here are some launches that got my attention during the previous week.

Amazon Bedrock now supports multi-agent collaboration – With the availability of multi-agent collaboration in Amazon Bedrock, you can create networks of specialized agents that communicate and coordinate under the guidance of a supervisor agent. You can build, deploy, and manage networks of AI agents that work together to execute complex, multi-step workflows efficiently.

Availability of fully managed DeepSeek-R1 model in Amazon Bedrock – AWS is the first cloud service provider (CSP) to deliver DeepSeek-R1 as a fully managed, generally available model. Use the capabilities of DeepSeek-R1 for your generative AI applications with a single API through this fully managed service in Amazon Bedrock.

Amazon SageMaker Unified Studio is now generally available – You can now use Amazon SageMaker Unified Studio as your single data and AI development environment, where you can find and access all of your organization’s data and work using the best tools for your specific needs. With the new simplified permissions management, you can easily bring your existing AWS resources into the unified studio. You’ll be able to find, access, and query your organization’s data and AI assets while collaborating with your team to securely build and share your analytics and AI artifacts—from data and models to generative AI applications.

Amazon Bedrock’s capabilities now generally available within Amazon SageMaker Unified Studio – SageMaker Unified Studio brings selected capabilities from Amazon Bedrock into SageMaker. You can now rapidly prototype, customize, and share generative AI applications using foundation models (FMs) and advanced features such as Amazon Bedrock Knowledge Bases, Amazon Bedrock Guardrails, Amazon Bedrock Agents, and Amazon Bedrock Flows to create tailored solutions aligned with your requirements and responsible AI guidelines all within SageMaker.

Amazon S3 Tables integration with Amazon SageMaker Lakehouse is now generally available – Amazon S3 Tables now seamlessly integrate with Amazon SageMaker Lakehouse, making it easy for you to query and join S3 Tables with data in S3 data lakes, Amazon Redshift data warehouses, and third-party data sources. S3 Tables deliver the first cloud object store with built-in Apache Iceberg support.

Amazon S3 Tables now support create and query table operations directly from the S3 console using Amazon Athena – Amazon S3 Tables adds create and query table support in the S3 console. With this new feature, you can now create a table, populate it with data, and query it directly from the S3 console using Amazon Athena, making it easier to get started and analyze data in S3 table buckets.

Amazon S3 reduces pricing for S3 object tagging by 35% – Amazon S3 reduces pricing for S3 object tagging by 35% in all AWS Regions to $0.0065 per 10,000 tags per month. Object tags are key-value pairs applied to S3 objects that can be created, updated, or deleted at any time during the lifetime of the object.

Serverless Land Patterns available in Visual Studio Code – Serverless Land‘s extensive application pattern library is now available directly into the Visual Studio Code (VS Code) IDE, making it easier for developers to build serverless applications. This integration eliminates the need to switch between your development environment and external resources when building serverless architectures by enabling you to browse, search, and implement pre-built serverless patterns directly in VS Code IDE.

Amplify Hosting Announces Skew Protection Support – AWS Amplify Hosting now offers Skew Protection, a feature that guarantees version consistency across your deployments. This feature ensures frontend requests are always routed to the correct server backend version—eliminating version skew and making deployments more reliable.

Amazon Route 53 Traffic Flow introduces a new visual editor to improve DNS policy editing – Amazon Route 53 Traffic Flow now offers an enhanced user interface for improved DNS traffic policy editing. With this release, you can more easily understand and change the way traffic is routed between users and endpoints using the new features of the visual editor.

From community.aws
Here are some of my favorite posts from community.aws. Create your AWS Builder ID to start sharing your tips and connect with fellow builders. Your Builder ID is a universal login credential that gives you access, beyond the AWS Management Console, to AWS tools and resources, including over 600 free training courses, community features, and developer tools such as Amazon Q Developer.

Seamless SQL Server Recovery on EC2 with AWS Systems Manager (Greg Vinton) – This guide explains how to use the AWSEC2-RestoreSqlServerDatabaseWithVss automation runbook to restore a Microsoft SQL Server database on an Amazon Elastic Compute Cloud (Amazon EC2) instance.

Secure Deployment Strategies in Amazon EKS with Azure DevOps (Abhishek Nanda) – Build and Deploy containerized applications on Amazon Elastic Kubernetes Service (Amazon EKS) using Azure DevOps.

Connect Your Favorite LLM Client to Bedrock (Qinjie Zhang) – It’s common to use desktop applications like MSTY, Chatbox AI, LM Studio to simplify the use of Large Language Models (LLM) models. This blog provides a step-by-step guide on how you can connect your favorite local LLM clients to Amazon Bedrock.

From PHP to Python with the help of Amazon Q Developer (Ricardo Sueiras) – In this blog post, Ricardo showcases how to use Amazon Q Developer CLI to refactor code from one programming language to another.

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events:

AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Milan, Italy (April 2), Bay Area – Security Edition (April 4), Timișoara, Romania (April 10), and Prague, Czech Republic (April 29).

AWS Innovate: Generative AI + Data – Join a free online conference focusing on generative AI and data innovations in Latin America on April 8.

AWS Summits – The AWS Summit season is coming along! Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Paris (April 9), Amsterdam (April 16), London (April 30), and Poland (May 5).

AWS re:Inforce (June 16–18) – Our annual learning event devoted to all things AWS Cloud security in Philadelphia, PA. Registration opens in March, so be ready to join more than 5,000 security builders and leaders.

AWS DevDays are free, technical events where developers can learn about some of the hottest topics in cloud computing. DevDays offer hands-on workshops, technical sessions, live demos, and networking with AWS technical experts and your peers. Register to access AWS DevDays sessions on demand.

That’s all for this week. Check back next Monday for another Weekly Roundup!

– Prasad

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

AWS Pi Day 2025: Data foundation for analytics and AI

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-pi-day-data-foundation-for-analytics-and-ai/

Every year on March 14 (3.14), AWS Pi Day highlights AWS innovations that help you manage and work with your data. What started in 2021 as a way to commemorate the fifteenth launch anniversary of Amazon Simple Storage Service (Amazon S3) has now grown into an event that highlights how cloud technologies are transforming data management, analytics, and AI.

This year, AWS Pi Day returns with a focus on accelerating analytics and AI innovation with a unified data foundation on AWS. The data landscape is undergoing a profound transformation as AI emerges in most enterprise strategies, with analytics and AI workloads increasingly converging around a lot of the same data and workflows. You need an easy way to access all your data and use all your preferred analytics and AI tools in a single integrated experience. This AWS Pi Day, we’re introducing a slate of new capabilities that help you build unified and integrated data experiences.

The next generation of Amazon SageMaker: The center of all your data, analytics, and AI
At re:Invent 2024, we introduced the next generation of Amazon SageMaker, the center of all your data, analytics, and AI. SageMaker includes virtually all the components you need for data exploration, preparation and integration, big data processing, fast SQL analytics, machine learning (ML) model development and training, and generative AI application development. With this new generation of Amazon SageMaker, SageMaker Lakehouse provides you with unified access to your data and SageMaker Catalog helps you to meet your governance and security requirements. You can read the launch blog post written by my colleague Antje to learn more details.

Core to the next generation of Amazon SageMaker is SageMaker Unified Studio, a single data and AI development environment where you can use all your data and tools for analytics and AI. SageMaker Unified Studio is now generally available.

SageMaker Unified Studio facilitates collaboration among data scientists, analysts, engineers, and developers as they work on data, analytics, AI workflows, and applications. It provides familiar tools from AWS analytics and artificial intelligence and machine learning (AI/ML) services, including data processing, SQL analytics, ML model development, and generative AI application development, into a single user experience.

SageMaker Unified Studio

SageMaker Unified Studio also brings selected capabilities from Amazon Bedrock into SageMaker. You can now rapidly prototype, customize, and share generative AI applications using foundation models (FMs) and advanced features such as Amazon Bedrock Knowledge Bases, Amazon Bedrock Guardrails, Amazon Bedrock Agents, and Amazon Bedrock Flows to create tailored solutions aligned with your requirements and responsible AI guidelines all within SageMaker.

Last but not least, Amazon Q Developer is now generally available in SageMaker Unified Studio. Amazon Q Developer provides generative AI powered assistance for data and AI development. It helps you with tasks like writing SQL queries, building extract, transform, and load (ETL) jobs, and troubleshooting, and is available in the Free tier and Pro tier for existing subscribers.

You can learn more about SageMaker Unified Studio in this recent blog post written by my colleague Donnie.

During re:Invent 2024, we also launched Amazon SageMaker Lakehouse as part of the next generation of SageMaker. SageMaker Lakehouse unifies all your data across Amazon S3 data lakes, Amazon Redshift data warehouses, and third-party and federated data sources. It helps you build powerful analytics and AI/ML applications on a single copy of your data. SageMaker Lakehouse gives you the flexibility to access and query your data in-place with Apache Iceberg–compatible tools and engines. In addition, zero-ETL integrations automate the process of bringing data into SageMaker Lakehouse from AWS data sources such as Amazon Aurora or Amazon DynamoDB and from applications such as Salesforce, Facebook Ads, Instagram Ads, ServiceNow, SAP, Zendesk, and Zoho CRM. The full list of integrations is available in the SageMaker Lakehouse FAQ.

Building a data foundation with Amazon S3
Building a data foundation is the cornerstone of accelerating analytics and AI workloads, enabling organizations to seamlessly manage, discover, and utilize their data assets at any scale. Amazon S3 is the world’s best place to build a data lake, with virtually unlimited scale, and it provides the essential foundation for this transformation.

I’m always astonished to learn about the scale at which we operate Amazon S3: It currently holds over 400 trillion objects, exabytes of data, and processes a mind-blowing 150 million requests per second. Just a decade ago, not even 100 customers were storing more than a petabyte (PB) of data on S3. Today, thousands of customers have surpassed the 1 PB milestone.

Amazon S3 stores exabytes of tabular data, and it averages over 15 million requests to tabular data per second. To help you reduce the undifferentiated heavy lifting when managing your tabular data in S3 buckets, we announced Amazon S3 Tables at AWS re:Invent 2024. S3 Tables are the first cloud object store with built-in support for Apache Iceberg. S3 tables are specifically optimized for analytics workloads, resulting in up to threefold faster query throughput and up to tenfold higher transactions per second compared to self-managed tables.

Today, we’re announcing the general availability of Amazon S3 Tables integration with Amazon SageMaker Lakehouse  Amazon S3 Tables now integrate with Amazon SageMaker Lakehouse, making it easy for you to access S3 Tables from AWS analytics services such as Amazon Redshift, Amazon Athena, Amazon EMR, AWS Glue, and Apache Iceberg–compatible engines such as Apache Spark or PyIceberg. SageMaker Lakehouse enables centralized management of fine-grained data access permissions for S3 Tables and other sources and consistently applies them across all engines.

For those of you who use a third-party catalog, have a custom catalog implementation, or only need basic read and write access to tabular data in a single table bucket, we’ve added new APIs that are compatible with the Iceberg REST Catalog standard. This enables any Iceberg-compatible application to seamlessly create, update, list, and delete tables in an S3 table bucket. For unified data management across all of your tabular data, data governance, and fine-grained access controls, you can also use S3 Tables with SageMaker Lakehouse.

To help you access S3 Tables, we’ve launched updates in the AWS Management Console. You can now create a table, populate it with data, and query it directly from the S3 console using Amazon Athena, making it easier to get started and analyze data in S3 table buckets.

The following screenshot shows how to access Athena directly from the S3 console.

S3 console : create table with AthenaWhen I select Query tables with Athena or Create table with Athena, it opens the Athena console on the correct data source, catalog, and database.

S3 Tables in Athena

Since re:Invent 2024, we’ve continued to add new capabilities to S3 Tables at a rapid pace. For example, we added schema definition support to the CreateTable API and you can now create up to 10,000 tables in an S3 table bucket. We also launched S3 Tables into eight additional AWS Regions, with the most recent being Asia Pacific (Seoul, Singapore, Sydney) on March 4, with more to come. You can refer to the S3 Tables AWS Regions page of the documentation to get the list of the eleven Regions where S3 Tables are available today.

Amazon S3 Metadata—announced during re:Invent 2024— has been generally available since January 27. It’s the fastest and easiest way to help you discover and understand your S3 data with automated, effortlessly-queried metadata that updates in near real time. S3 Metadata works with S3 object tags. Tags help you logically group data for a variety of reasons, such as to apply IAM policies to provide fine-grained access, specify tag-based filters to manage object lifecycle rules, and selectively replicate data to another Region. In Regions where S3 Metadata is available, you can capture and query custom metadata that is stored as object tags. To reduce the cost associated with object tags when using S3 Metadata, Amazon S3 reduced pricing for S3 object tagging by 35 percent in all Regions, making it cheaper to use custom metadata.

AWS Pi Day 2025
Over the years, AWS Pi Day has showcased major milestones in cloud storage and data analytics. This year, the AWS Pi Day virtual event will feature a range of topics designed for developers and technical decision-makers, data engineers, AI/ML practitioners, and IT leaders. Key highlights include deep dives, live demos, and expert sessions on all the services and capabilities I discussed in this post.

By attending this event, you’ll learn how you can accelerate your analytics and AI innovation. You’ll learn how you can use S3 Tables with native Apache Iceberg support and S3 Metadata to build scalable data lakes that serve both traditional analytics and emerging AI/ML workloads. You’ll also discover the next generation of Amazon SageMaker, the center for all your data, analytics, and AI, to help your teams collaborate and build faster from a unified studio, using familiar AWS tools with access to all your data whether it’s stored in data lakes, data warehouses, or third-party or federated data sources.

For those looking to stay ahead of the latest cloud trends, AWS Pi Day 2025 is an event you can’t miss. Whether you’re building data lakehouses, training AI models, building generative AI applications, or optimizing analytics workloads, the insights shared will help you maximize the value of your data.

Tune in today and explore the latest in cloud data innovation. Don’t miss the opportunity to engage with AWS experts, partners, and customers shaping the future of data, analytics, and AI.

If you missed the virtual event on March 14, you can visit the event page at any time—we will keep all the content available on-demand there!

— seb


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Amazon S3 Tables integration with Amazon SageMaker Lakehouse is now generally available

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/amazon-s3-tables-integration-with-amazon-sagemaker-lakehouse-is-now-generally-available/

At re:Invent 2024, we launched Amazon S3 Tables, the first cloud object store with built-in Apache Iceberg support to streamline storing tabular data at scale, and Amazon SageMaker Lakehouse to simplify analytics and AI with a unified, open, and secure data lakehouse. We also previewed S3 Tables integration with Amazon Web Services (AWS) analytics services for you to stream, query, and visualize S3 Tables data using Amazon Athena, Amazon Data Firehose, Amazon EMR, AWS Glue, Amazon Redshift, and Amazon QuickSight.

Our customers wanted to simplify the management and optimization of their Apache Iceberg storage, which led to the development of S3 Tables. They were simultaneously working to break down data silos that impede analytics collaboration and insight generation using the SageMaker Lakehouse. When paired with S3 Tables and SageMaker Lakehouse in addition to built-in integration with AWS analytics services, they can gain a comprehensive platform unifying access to multiple data sources enabling both analytics and machine learning (ML) workflows.

Today, we’re announcing the general availability of Amazon S3 Tables integration with Amazon SageMaker Lakehouse to provide unified S3 Tables data access across various analytics engines and tools. You can access SageMaker Lakehouse from Amazon SageMaker Unified Studio, a single data and AI development environment that brings together functionality and tools from AWS analytics and AI/ML services. All S3 tables data integrated with SageMaker Lakehouse can be queried from SageMaker Unified Studio and engines such as Amazon Athena, Amazon EMR, Amazon Redshift, and Apache Iceberg-compatible engines like Apache Spark or PyIceberg.

With this integration, you can simplify building secure analytic workflows where you can read and write to S3 Tables and join with data in Amazon Redshift data warehouses and third-party and federated data sources, such as Amazon DynamoDB or PostgreSQL.

You can also centrally set up and manage fine-grained access permissions on the data in S3 Tables along with other data in the SageMaker Lakehouse and consistently apply them across all analytics and query engines.

S3 Tables integration with SageMaker Lakehouse in action
To get started, go to the Amazon S3 console and choose Table buckets from the navigation pane and select Enable integration to access table buckets from AWS analytics services.

Now you can create your table bucket to integrate with SageMaker Lakehouse. To learn more, visit Getting started with S3 Tables in the AWS documentation.

1. Create a table with Amazon Athena in the Amazon S3 console
You can create a table, populate it with data, and query it directly from the Amazon S3 console using Amazon Athena with just a few steps. Select a table bucket and select Create table with Athena, or you can select an existing table and select Query table with Athena.

2. Create tables with Athena

When you want to create a table with Athena, you should first specify a namespace for your table. The namespace in an S3 table bucket is equivalent to a database in AWS Glue, and you use the table namespace as the database in your Athena queries.

Choose a namespace and select Create table with Athena. It goes to the Query editor in the Athena console. You can create a table in your S3 table bucket or query data in the table.

2. Query with Athena

2. Query with SageMaker Lakehouse in the SageMaker Unified Studio
Now you can access unified data across S3 data lakes, Redshift data warehouses, third-party and federated data sources in SageMaker Lakehouse directly from SageMaker Unified Studio.

To get started, go to the SageMaker console and create a SageMaker Unified Studio domain and project using a sample project profile: Data Analytics and AI-ML model development. To learn more, visit Create an Amazon SageMaker Unified Studio domain in the AWS documentation.

After the project is created, navigate to the project overview and scroll down to project details to note down the project role Amazon Resource Name (ARN).

3. Project details in SageMaker Unified Studio

Go to the AWS Lake Formation console and grant permissions for AWS Identity and Access Management (IAM) users and roles. In the in the Principals section, select the <project role ARN> noted in the previous paragraph. Choose Named Data Catalog resources in the LF-Tags or catalog resources section and select the table bucket name you created for Catalogs. To learn more, visit Overview of Lake Formation permissions in the AWS documentation.

4. Grant permissions in Lake Formation console

When you return to SageMaker Unified Studio, you can see your table bucket project under Lakehouse in the Data menu in the left navigation pane of project page. When you choose Actions, you can select how to query your table bucket data in Amazon Athena, Amazon Redshift, or JupyterLab Notebook.

5. S3 Tables in Unified Studio

When you choose Query with Athena, it automatically goes to Query Editor to run data query language (DQL) and data manipulation language (DML) queries on S3 tables using Athena.

Here is a sample query using Athena:

select * from "s3tablecatalog/s3tables-integblog-bucket”.”proddb"."customer" limit 10;

6. Athena query in Unified Studio

To query with Amazon Redshift, you should set up Amazon Redshift Serverless compute resources for data query analysis. And then you choose Query with Redshift and run SQL in the Query Editor. If you want to use JupyterLab Notebook, you should create a new JupyterLab space in Amazon EMR Serverless.

3. Join data from other sources with S3 Tables data
With S3 Tables data now available in SageMaker Lakehouse, you can join it with data from data warehouses, online transaction processing (OLTP) sources like relational or non-relational database, Iceberg tables, and other third party sources to gain more comprehensive and deeper insights.

For example, you can add connections to data sources such as Amazon DocumentDB, Amazon DynamoDB, Amazon Redshift, PostgreSQL, MySQL, Google BigQuery, or Snowflake and combine data using SQL without extract, transform, and load (ETL) scripts.

Now you can run the SQL query in the Query editor to join the data in the S3 Tables with the data in the DynamoDB.

Here is a sample query to join between Athena and DynamoDB:

select * from "s3tablescatalog/s3tables-integblog-bucket"."blogdb"."customer", 
              "dynamodb1"."default"."customer_ddb" where cust_id=pid limit 10;

To learn more about this integration, visit Amazon S3 Tables integration with Amazon SageMaker Lakehouse in the AWS documentation.

Now available
S3 Tables integration with SageMaker Lakehouse is now generally available in all AWS Regions where S3 Tables are available. To learn more, visit the S3 Tables product page and the SageMaker Lakehouse page.

Give S3 Tables a try in the SageMaker Unified Studio today and send feedback to AWS re:Post for Amazon S3 and AWS re:Post for Amazon SageMaker or through your usual AWS Support contacts.

In the annual celebration of the launch of Amazon S3, we will introduce more awesome launches for Amazon S3 and Amazon SageMaker. To learn more, join the AWS Pi Day event on March 14.

— Channy

—

How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Best practices for rapidly deploying Landing Zone Accelerator on AWS

Post Syndicated from Lei Shi original https://aws.amazon.com/blogs/devops/best-practices-for-rapidly-deploying-landing-zone-accelerator-on-aws/

Landing Zone Accelerator on AWS (LZA) enables customers to deploy a flexible, configuration-driven solution to establish a landing zone while also leveraging AWS Control Tower. At AWS Professional Services, we’ve helped customers deploy and configure LZA hundreds of times. A common request we encounter is integrating LZA configuration into customers’ existing GitOps workflows. GitOps has emerged as a leading model for Infrastructure as Code (IaC), helping organizations automate and manage their cloud infrastructure. The model uses Git repositories as the single source of truth for infrastructure configuration, enabling teams to maintain consistent, version-controlled environments.

In this blog, we will focus on common LZA implementation steps based on our experience, helping customers jump-start their LZA environment and implement GitOps for their AWS infrastructure management. First, we will demonstrate how to leverage LZA while complying with your organization’s policies such as private package repositories. Next, we will guide you through a new installation of LZA that takes advantage of an auto-generated starter set of configuration files. Finally, we will direct you to another blog post that will enable you to leverage GitOps for ongoing management of your LZA configuration.

Architecture overview

The LZA solution leverages two distinct repositories; one for the LZA source code, and another for your organization’s specific configuration files. LZA creates two separate AWS CodePipelines , which are used to install the LZA solution and apply your organization’s specific configuration. Figure 1 illustrates the association between repositories and pipelines. By default, when installing LZA, the solution uses GitHub as the source and pulls the installation files published by AWS from the official LZA GitHub repository.

a diagram with icons illustrating LZA solution components

Figure 1. Landing Zone Accelerator solution components

Deploy LZA as a new install

Step 1: Preparing your enterprise private GitHub to host LZA source code.
Customers may choose to deploy LZA from the official AWS GitHub repository for LZA, but we often we find customers have policies in place that require these types of packages to be deployed from a private repository managed by the organization. For customers using GitHub privately in their enterprise, this can be as easy as cloning the LZA source code repository into your own private GitHub repository, enabling you to take advantage of policies and controls within your organization. Before moving to the next step, take a moment and clone the repository into your own private repository. A GitHub personal access token stored in AWS Secrets Manager is required to enable the stack to access your private repository. Before deploying LZA, follow these instructions to enable stack access to your repository.

Step 2: In the organization management account, install LZA as a CloudFormation Stack.

To get started, we will be going through a new installation of the LZA solution. The following steps provide specific parameter options to the CloudFormation template to support a new installation of LZA.

Specify the following parameters for Source Code Repository Configuration, see Figure 2.

  1. For Stack name, specify a name you like.
  2. For Source Location, choose github.
  3. For Repository Owner, specify your GitHub account owner ID.
  4. For Repository Name, specify your cloned LZA source code repository
  5. For Branch Name, specify the branch name of your LZA source code repository.

a screenshot of a set of parameters setting of LZA source code repo in a cloudformation stack

Figure 2. LZA installer stack parameters – source code repository

Specify the following parameters for Configuration Repository Configuration, see Figure 3.

  1. For Configuration Repository Location, choose s3.
  2. For Use Existing Config Repository, choose No.
  3. For Existing Config Repository Name, Existing Config Repository Branch Name, Existing Config Repository Owner, and Existing Config Repository CodeConnection ARN, leave blank.

We intentionally want to use S3 for the configuration repository because as the LZA solution is installed, it will auto-generate a set of starter configuration YAML files and deploy them for us in S3. This makes it very easy to get started with an initial set of customized YAML files for your environment. We choose “No” in the Use Existing Config Repository field, to have LZA to perform a new LZA installation.

a screenshot of a set of parameters setting of LZA configuration repo in a cloudformation stack

Figure 3. LZA installer stack parameters – configuration repository

  1. Choose Next, and complete the remainder of the stack settings.
  2. Finally, choose Create stack to launch the CloudFormation stack.

The installer stack typically takes minutes to complete (See Figure 4).

a screenshot showing LZA installation cloudformation stack completed successfully

Figure 4. LZA installer stack completion

Step 3: Validate two LZA pipelines are created and successfully completed in AWS CodePipeline console.

After the CloudFormation stack completes, open the AWS CodePipeline console. You’ll see a new pipeline named “AWSAccelerator-Installer” running (See Figure 5). This is the LZA Installer pipeline, and it’s connected to the GitHub source repository you specified in Step 2 above with parameters from 2 to 5. This Installer pipeline automatically generates a set of LZA configuration files stored as a compressed ZIP archive in Amazon S3. It will be designated as configuration repository of the LZA solution.

a screenshot showing LZA installer pipeline created in AWS CodePipeline successfully

Figure 5. AWSAccelerator-Installer pipeline creation

When the AWSAccelerator-Installer pipeline completes, the solution automatically creates and runs a second pipeline named “AWSAccelerator-Pipeline” as shown in Figure 6. This pipeline connects to both the GitHub source repository, and the newly created configuration repository in Amazon S3. The AWSAccelerator-Pipeline is the pipeline that manages your landing zone deployment and customization.

a screenshot showing LZA core pipeline created in AWS CodePipeline successfully

Figure 6. AWSAccelerator-Pipeline created from the AWSAccelerator-Installer pipeline

After the AWSAccelerator-Pipeline completes, your LZA solution is ready for customization.

Step 4: Migrate the LZA configuration repository from S3 to GitHub

With the AWSAccelerator-Pipeline completed, your initial landing zone is now deployed, leveraging the configuration stored in your S3 bucket. For some customers, they may need to ensure that changes to the landing zone configuration are controlled through their existing GitOps processes and tooling. See Figure 7 as an example where the S3 configuration files have been copied to a customer owned GitHub repository. This transition step can be performed in future LZA upgrade window when there is a new release of LZA source code, or right after the initial LZA installation completes in Step 3. For more information on migrating from S3 to GitHub, follow this guide to configure your AWSAccelerator-Pipelines with AWS CodeConnection.

a diagram with icons illustrating LZA solution new components with LZA configuration repo migrated to GitHub

Figure 7. CodeConnection based LZA Configuration Repository

Conclusion

In this post, we explored key steps to streamline your LZA implementation journey. By demonstrating how to work with your private package repositories, providing guidance on leveraging auto-generated configuration files, and introducing GitOps-based management, we’ve outlined a practical path to establish and maintain a robust AWS infrastructure foundation. These approaches can significantly reduce the time and complexity typically associated with LZA deployments while ensuring compliance with organizational policies. We encourage you to try these implementation steps and explore the referenced resources to enhance your AWS cloud operations. For more information about Landing Zone Accelerator, visit the AWS Landing Zone Accelerator on GitHub.

About the authors

author photo of Lei Shi

Lei Shi

Lei Shi is a Delivery Consultant at AWS Professional Services, where he transforms complex cloud challenges into elegant solutions. He focuses on enabling organizations to build secure and scalable cloud environments throughout their AWS journey.

author photo of Adam Spicer

Adam Spicer

Adam Spicer is a Principal Cloud Architect for AWS Professional Services. He works with enterprise customers to design and build their cloud infrastructure and automation to accelerate their migration to AWS. He is an avid FSU Seminole fan who loves to be on outdoor adventures with his family.

How to restrict Amazon S3 bucket access to a specific IAM role

Post Syndicated from Chris Craig original https://aws.amazon.com/blogs/security/how-to-restrict-amazon-s3-bucket-access-to-a-specific-iam-role/

February 14, 2025: This post was updated with the recommendation to restrict S3 bucket access to an IAM role by using the aws:PrincipalArn condition key instead of the aws:userid condition key.

April 2, 2021: In the section “Granting cross-account bucket access to a specific IAM role,” we updated the second policy to fix an error.

July 11, 2016: This post was first published.


Customers often ask how to limit access to an Amazon Simple Storage Service (Amazon S3) bucket to only a specific AWS Identity and Access Management (IAM) user or role. A popular approach has been to use the Principal element to list the users or roles who need access to the bucket. However, the Principal element needs the exact values of the user ARN, role ARN, or assumed-role ARN. It does not support using a wildcard (*) to include all role sessions, nor does it allow you to use policy variables.

In this blog post, we show how to restrict S3 bucket access to a specific IAM role or user within an account by using the Conditions element. Even if another user in the same account has an Admin policy or a policy with s3:*, they will be denied access if they are not explicitly listed in the Conditions element. You can use this approach, for example, to limit access to a bucket with sensitive content or additional security requirements.

Solution overview

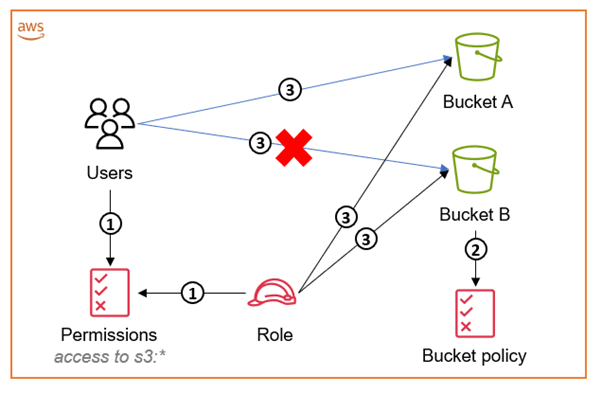
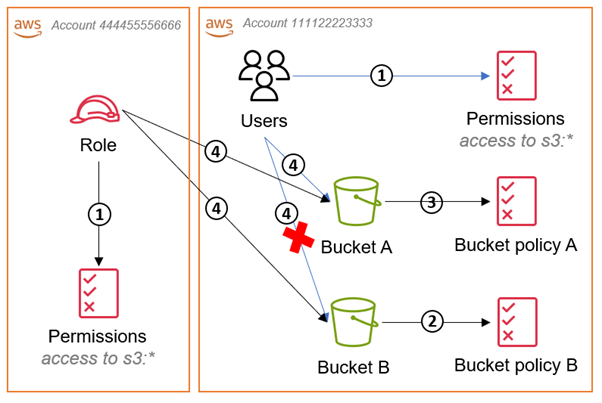
The solution in this post uses a bucket policy to restrict access to an S3 bucket, even if an entity has access to the full API of S3 through an attached identity-based policy. The following diagram illustrates how this works for accessing an S3 bucket within the same account as your IAM user or IAM role. We recommend that you use IAM roles, and only use IAM users for use cases that aren’t supported by federated users.

Figure 1: Diagram illustrating how to access an S3 bucket within the same account as your IAM user or IAM role

Figure 1: Diagram illustrating how to access an S3 bucket within the same account as your IAM user or IAM role

The workflow in Figure 1 is as follows:

  1. The IAM user’s policy and the IAM role’s identity-based policy grant access to “s3:*”.
  2. The S3 bucket policy associated with Bucket B restricts access to only the IAM role. This means that only the IAM role is able to access its content.
  3. Both the IAM user and the IAM role can access other S3 buckets (for example, Bucket A) in the account. The IAM role is able to access both buckets, but the user can access only the S3 buckets without the bucket policy attached to them. Even though both the role and the user have full “s3:*” permissions, the bucket policy negates access to the bucket for anyone that has not assumed the role.

The main difference in the cross-account approach is that every bucket must have a bucket policy attached to allow access to the IAM role from the other account. The following diagram illustrates how this works in a cross-account deployment scenario.

Figure 2: Diagram illustrating how to access an S3 bucket in a different account than your IAM role

Figure 2: Diagram illustrating how to access an S3 bucket in a different account than your IAM role

The workflow in Figure 2 is as follows:

  1. The IAM role’s identity-based policy and the IAM users’ policy in the bucket account both grant access to “s3:*”
  2. Bucket policy B denies access to all IAM users and roles except the role specified, and the policy defines what the role is allowed to do with the bucket.
  3. Bucket policy A allows access to the IAM role from the other account.
  4. The IAM user and IAM role can both access Bucket A because the IAM user is in the same account and there is an explicit Allow in bucket policy A for the role. The role can access both buckets because the Deny in bucket policy B is only for principals other than the IAM role.

Using the aws:PrincipalArn condition

You can use different types of condition keys to compare details about the principal making the request with the principal properties that you specify in the policy. We recommend that you use the aws:PrincipalArn key. The aws:PrincipalArn key compares the Amazon Resource Name (ARN) of the principal that made the request with the ARN that you specify in the policy.

You could also use the aws:userid policy variable to uniquely identify a user or role in their explicit Deny statements. There is added complexity with using aws:userid to find the value because you have to perform an API call using valid credentials. When working with IAM roles this activity has additional complexity because you are required to get the AssumedRoleUser information, which will not only include the unique role ID, but also the role-session-name that was provided while assuming the role. For example, the aws:userid for an AssumedRoleUser will be as follows:

aws:userid – AROADBQP57FF2AEXAMPLE:role-session-name

It becomes inconvenient to manage and track these IDs when you have a large list of users and roles to be included in the policy.

To mitigate these challenges, we recommend that you use the aws:PrincipalArn condition key. For IAM roles, the request context returns the ARN of the role, not the ARN of the user that assumed the role. AWS recommends that you specify the ARN for resources in policies instead of unique IDs and that you perform IAM policy audits on a periodic basis. Let’s look at how to use the condition key in an IAM policy.

Granting same-account bucket access to a specific role

When accessing a bucket from within the same account, in most cases it is not necessary to use a bucket policy because the policy defines access that is already granted by the user’s direct IAM policy. S3 bucket policies are usually used for cross-account access, but you can also use them to restrict access through an explicit Deny. The Deny would be applied to all principals whether they were in the same account as the bucket or within a different account.

In this case, you use the IAM user or role ARN with the aws:PrincipalArn condition key in a StringNotEquals or StringNotLike condition with a wildcard string. In addition, you use the aws:PrincipalARN key to compare the ARN of the principal that made the request with the ARN that you specify in the policy. Using a conditional logic element allows for the use of a wildcard string to allow for any role session name to be accepted.

Once you have the ARN of the role to which you want to allow access, you need to block the access of other users from within the same account as the bucket. An example policy to block access to the bucket and its objects for users that are not using the IAM role credentials would look like the following.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Deny",
      "Principal": "*",
      "Action": "s3:*",
      "Resource": [
        "arn:aws:s3:::amzn-s3-demo-bucket",
        "arn:aws:s3:::amzn-s3-demo-bucket/*"
      ],
      "Condition": {
        "StringNotEquals": {
          "aws:PrincipalArn": [
            "arn:aws:iam::111122223333:role/<ROLE-NAME>"
          ]
        }
      }
    }
  ]
}

Use this same policy for IAM users as shown below.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Deny",
      "Principal": "*",
      "Action": "s3:*",
      "Resource": [
        "arn:aws:s3:::amzn-s3-demo-bucket",
        "arn:aws:s3:::amzn-s3-demo-bucket/*"
      ],
      "Condition": {
        "StringNotEquals": {
          "aws:PrincipalARN": [
            "arn:aws:iam::111122223333:role/<ROLE-NAME>”,
            “arn:aws:iam::111122223333:user/<USER-NAME>"
          ]
        }
      }
    }
  ]
}

Granting cross-account bucket access to a specific IAM role

When granting cross-account bucket access to an IAM user or role, you must define what the IAM user or role is allowed to do with the granted access. Learn more about the permissions needed to allow an IAM entity to access a bucket via the CLI/API and the console in Writing IAM Policies: How to Grant Access to an Amazon S3 Bucket. Using the information found in this blog post, an example bucket policy would look like the following.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Principal": {
                "AWS": "arn:aws:iam::111122223333:role/<ROLE-NAME>"
            },
            "Action": "s3:ListBucket",
            "Resource": "arn:aws:s3:::amzn-s3-demo-bucket"
        },
        {
            "Effect": "Allow",
            "Principal": {
                "AWS": "arn:aws:iam::111122223333:role/<ROLE-NAME>"
            },
            "Action": [
                "s3:GetObject",
                "s3:PutObject",
                "s3:DeleteObject"
            ],
            "Resource": "arn:aws:s3:::amzn-s3-demo-bucket/*"
        },
        {
            "Effect": "Deny",
            "Principal": "*",
            "Action": "s3:*",
            "Resource": [
                "arn:aws:s3:::amzn-s3-demo-bucket",
                "arn:aws:s3:::amzn-s3-demo-bucket/*"
            ],
            "Condition": {
                "StringNotEquals": {
                    "aws:PrincipalARN": [
                        "arn:aws:iam::111122223333:role/<ROLE-NAME>"
                    ]
                }
            }
        }
    ]
}

To grant access to an IAM user in another account, you need to add the ARN for the IAM user to the aws:PrincipalArn condition as outlined in the previous section of this blog post. In addition to the aws:PrincipalArn condition, you would also need to add the IAM user’s full ARN to the Principal element of these policies. An example policy is shown below.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Principal": [
                {
                    "AWS": [
                        "arn:aws:iam::444455556666:role/<ROLE-NAME>”,
                        “arn:aws:iam::444455556666:user/<USER-NAME>"
                    ]
                }
            ],
            "Action": "s3:ListBucket",
            "Resource": "arn:aws:s3:::amzn-s3-demo-bucket"
        },
        {
            "Effect": "Allow",
            "Principal": [
                {
                    "AWS": [
                        "arn:aws:iam::444455556666:role/<ROLE-NAME>”,
                        “arn:aws:iam::444455556666:user/<USER-NAME>"
                    ]
                }
            ],
            "Action": [
                "s3:GetObject",
                "s3:PutObject",
                "s3:DeleteObject"
            ],
            "Resource": "arn:aws:s3:::amzn-s3-demo-bucket/*"
        },
        {
            "Effect": "Deny",
            "Principal": "*",
            "Action": "s3:*",
            "Resource": [
                "arn:aws:s3:::amzn-s3-demo-bucket",
                "arn:aws:s3:::amzn-s3-demo-bucket/*"
            ],
            "Condition": {
                "StringNotEquals": {
                    "aws:PrincipalARN": [
                        "arn:aws:iam::444455556666:role/<ROLE-NAME>”,
                        “arn:aws:iam::444455556666:user/<USER-NAME>"
                    ]
                }
            }
        }
    ]
}

In addition to including role permissions in the bucket policy, you need to define these permissions in the IAM user’s or role’s user policy. The permissions are added to a customer managed policy and attached to the role or user in the IAM console, with the following example policy document.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": "s3:ListAllMyBuckets",
      "Resource": "*"
    },
    {
      "Effect": "Allow",
      "Action": "s3:ListBucket",
      "Resource": "arn:aws:s3:::amzn-s3-demo-bucket"
    },
    {
      "Effect": "Allow",
      "Action": [
        "s3:GetObject",
        "s3:PutObject",
        "s3:DeleteObject"
      ],
      "Resource": "arn:aws:s3:::amzn-s3-demo-bucket/*"
    }
  ]
}

By following the guidance in this post, you restrict S3 bucket access to a specific IAM role or user in same-account and cross-account scenarios, even if the user has an Admin policy or a policy with “s3:*”. There are many applications of this logic in which requirements will vary across use cases. We recommend to employ the principle of least privilege wherever possible, and to grant only the minimum permissions that are required to perform necessary tasks.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Identity and Access Management re:Post or contact AWS Support.
 

Chris Craig

The original author of this blog post is no longer at AWS. In 2016, when this post was first published, we did not include author bios.
Laura Verghote
Laura Verghote

Laura is a Senior Solutions Architect for public sector customers in the Europe, Middle East, and Africa (EMEA) region. She works with customers to design and build solutions in the AWS Cloud, bridging the gap between complex business requirements and technical solutions. She joined AWS as a technical trainer and has wide experience delivering training content to developers, administrators, architects, and partners across EMEA.
Ashwin Phadke
Ashwin Phadke

Ashwin is a Senior Solutions Architect working with large enterprises and independent software vendor (ISV) customers to build highly available, scalable, and secure applications, and to help them successfully navigate their cloud journeys. He is passionate about information security and enjoys working on creative solutions for customers’ security challenges.

AWS Weekly Roundup: DeepSeek-R1, S3 Metadata, Elastic Beanstalk updates, and more (February 3, 2024)

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-deepseek-r1-s3-metadata-elastic-beanstalk-updates-and-more-february-3-2024/

Last week, I had an amazing time attending AWS Community Day Thailand in Bangkok. This event came at an exciting time, following the recent launch of the AWS Asia Pacific (Bangkok) Region. We had over 300 attendees and featured 15 speakers from the community, including an AWS Hero and 4 AWS Community Builders who shared their technical expertise and experiences.

The highlight was definitely Jeff Barr, AWS Vice President & Chief Evangelist, delivering an inspiring keynote titled “Next-Generation Software Development”, which set the perfect tone for the day. The day kicked off with welcoming remarks from Vatsun Thirapatarapong, AWS Country Manager for Thailand, and was made even more special thanks to the tremendous support from both the AWS User Group volunteers and the AWS Thailand team.

Here’s a photo capturing the excitement from the event: 

Last week’s AWS Launches
There are 30+ launches last week and here are some launches that caught my attention:

DeepSeek-R1 models now available on AWS — Channy wrote on how you can now deploy DeepSeek-R1 models in Amazon Bedrock and Amazon SageMaker AI. This helps you to build and scale generative AI applications with minimal infrastructure investment.

Amazon S3 Tables increases table limit to 10,000 per bucket — S3 Tables now supports creating up to 10,000 tables in each table bucket, allowing you to scale up to 100,000 tables across 10 buckets within an AWS Region per account.

Amazon S3 Metadata now generally available — S3 Metadata provides automated and easily queried metadata that updates in near real-time, simplifying business analytics and real-time inference applications. It supports both system-defined and custom metadata, including integration with AWS analytics services.

AWS Amplify adds TypeScript Data client support for Lambda functions — Developers can now use the Amplify Data client within AWS Lambda functions, enabling consistent type-safe data operations across frontend and backend applications.

AWS Elastic Beanstalk adds Python 3.13, .NET 9, and PHP 8.4 support on Amazon Linux 2023 — AWS Elastic Beanstalk brings the latest language features and improvements to application deployments while benefiting from Amazon Linux 2023 enhanced security and performance features.

From community.aws
Here’s my top 5 personal favorites posts from community.aws:

Upcoming AWS and community events
Check your calendars and sign up for upcoming AWS and community events:

  • AWS Korea re:Invent reCap Online, February 2-4 — A virtual event recapping key announcements and innovations from re:Invent 2023 for the Korean audience.
  • AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs. Upcoming AWS Community Day is in Ahmedabad (February 8).
  • AWS Public Sector Day London, February 27 — Join public sector leaders and innovators to explore how AWS is enabling digital transformation in government, education, and healthcare.
  • AWS Innovate GenAI + Data Edition — A free online conference focusing on generative AI and data innovations. Available in multiple Regions: APJC and EMEA (March 6), North America (March 13), Greater China Region (March 14), and Latin America (April 8).

Browse more upcoming AWS led in-person and virtual developer-focused events.

AWS Community re:Invent re:Caps

Lastly, if you want to learn about top announcements and innovations from AWS re:Invent, the AWS Community shares a summary from a community perspective of these announcements so you can get up to speed. Download the AWS Community re:Invent re:Caps deck. 

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Donnie

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

How Open Universities Australia modernized their data platform and significantly reduced their ETL costs with AWS Cloud Development Kit and AWS Step Functions

Post Syndicated from Michael Davies original https://aws.amazon.com/blogs/big-data/how-open-universities-australia-modernized-their-data-platform-and-significantly-reduced-their-etl-costs-with-aws-cloud-development-kit-and-aws-step-functions/

This is a guest post co-authored by Michael Davies from Open Universities Australia.

At Open Universities Australia (OUA), we empower students to explore a vast array of degrees from renowned Australian universities, all delivered through online learning. We offer students alternative pathways to achieve their educational aspirations, providing them with the flexibility and accessibility to reach their academic goals. Since our founding in 1993, we have supported over 500,000 students to achieve their goals by providing pathways to over 2,600 subjects at 25 universities across Australia.

As a not-for-profit organization, cost is a crucial consideration for OUA. While reviewing our contract for the third-party tool we had been using for our extract, transform, and load (ETL) pipelines, we realized that we could replicate much of the same functionality using Amazon Web Services (AWS) services such as AWS Glue, Amazon AppFlow, and AWS Step Functions. We also recognized that we could consolidate our source code (much of which was stored in the ETL tool itself) into a code repository that could be deployed using the AWS Cloud Development Kit (AWS CDK). By doing so, we had an opportunity to not only reduce costs but also to enhance the visibility and maintainability of our data pipelines.

In this post, we show you how we used AWS services to replace our existing third-party ETL tool, improving the team’s productivity and producing a significant reduction in our ETL operational costs.

Our approach

The migration initiative consisted of two main parts: building the new architecture and migrating data pipelines from the existing tool to the new architecture. Often, we would work on both in parallel, testing one component of the architecture while developing another at the same time.

From early in our migration journey, we began to define a few guiding principles that we would apply throughout the development process. These were:

  • Simple and modular – Use simple, reusable design patterns with as few moving parts as possible. Structure the code base to prioritize ease of use for developers.
  • Cost-effective – Use resources in an efficient, cost-effective way. Aim to minimize situations where resources are running idly while waiting for other processes to be completed.
  • Business continuity – As much as possible, make use of existing code rather than reinventing the wheel. Roll out updates in stages to minimize potential disruption to existing business processes.

Architecture overview

The following Diagram 1 is the high-level architecture for the solution.

Diagram 1: Overall architecture of the solution, using AWS Step Functions, Amazon Redshift and Amazon S3

The following AWS services were used to shape our new ETL architecture:

  • Amazon Redshift – A fully managed, petabyte-scale data warehouse service in the cloud. Amazon Redshift served as our central data repository, where we would store data, apply transformations, and make data available for use in analytics and business intelligence (BI). Note: The provisioned cluster itself was deployed separately from the ETL architecture and remained unchanged throughout the migration process.
  • AWS Cloud Development Kit (AWS CDK) – The AWS Cloud Development Kit (AWS CDK) is an open-source software development framework for defining cloud infrastructure in code and provisioning it through AWS CloudFormation. Our infrastructure was defined as code using the AWS CDK. As a result, we simplified the way we defined the resources we wanted to deploy while using our preferred coding language for development.
  • AWS Step Functions – With AWS Step Functions, you can create workflows, also called State machines, to build distributed applications, automate processes, orchestrate microservices, and create data and machine learning pipelines. AWS Step Functions can call over 200 AWS services including AWS Glue, AWS Lambda, and Amazon Redshift. We used the AWS Step Function state machines to define, orchestrate, and execute our data pipelines.
  • Amazon EventBridge – We used Amazon EventBridge, the serverless event bus service, to define the event-based rules and schedules that would trigger our AWS Step Functions state machines.
  • AWS Glue – A data integration service, AWS Glue consolidates major data integration capabilities into a single service. These include data discovery, modern ETL, cleansing, transforming, and centralized cataloging. It’s also serverless, which means there’s no infrastructure to manage. includes the ability to run Python scripts. We used it for executing long-running scripts, such as for ingesting data from an external API.
  • AWS Lambda – AWS Lambda is a highly scalable, serverless compute service. We used it for executing simple scripts, such as for parsing a single text file.
  • Amazon AppFlow – Amazon AppFlow enables simple integration with software as a service (SaaS) applications. We used it to define flows that would periodically load data from selected operational systems into our data warehouse.
  • Amazon Simple Storage Service (Amazon S3) – An object storage service offering industry-leading scalability, data availability, security, and performance. Amazon S3 served as our staging area, where we would store raw data prior to loading it into other services such as Amazon Redshift. We also used it as a repository for storing code that could be retrieved and used by other services.

Where practical, we made use of the file structure of our code base for defining resources. We set up our AWS CDK to refer to the contents of a specific directory and define a resource (for example, an AWS Step Functions state machine or an AWS Glue job) for each file it found in that directory. We also made use of configuration files so we could customize the attributes of specific resources as required.

Details on specific patterns

In the above architecture Diagram 1, we showed multiple flows by which data could be ingested or unloaded from our Amazon Redshift data warehouse. In this section, we highlight four specific patterns in more detail which were utilized in the final solution.

Pattern 1: Data transformation, load, and unload

Several of our data pipelines included significant data transformation steps, which were primarily performed through SQL statements executed by Amazon Redshift. Others required ingestion or unloading of data from the data warehouse, which could be performed efficiently using COPY or UNLOAD statements executed by Amazon Redshift.

In keeping with our aim of using resources efficiently, we sought to avoid running these statements from within the context of an AWS Glue job or AWS Lambda function because these processes would remain idle while waiting for the SQL statement to be completed. Instead, we opted for an approach where SQL execution tasks would be orchestrated by an AWS Step Functions state machine, which would send the statements to Amazon Redshift and periodically check their progress before marking them as either successful or failed. The following Diagram 2 shows this workflow.

Data transformation, load, and unload

Diagram 2: Data transformation, load, and unload pattern using Amazon Lambda and Amazon Redshift within an AWS Step Function

Pattern 2: Data replication using AWS Glue

In cases where we needed to replicate data from a third-party source, we used AWS Glue to run a script that would query the relevant API, parse the response, and store the relevant data in Amazon S3. From here, we used Amazon Redshift to ingest the data using a COPY statement. The following Diagram 3 shows this workflow.

Image 3: Copying from external API to Redshift with AWS Glue

Diagram 3: Copying from external API to Redshift with AWS Glue

Note: Another option for this step would be to use Amazon Redshift auto-copy, but this wasn’t available at time of development.

Pattern 3: Data replication using Amazon AppFlow

For certain applications, we were able to use Amazon AppFlow flows in place of AWS Glue jobs. As a result, we could abstract some of the complexity of querying external APIs directly. We configured our Amazon AppFlow flows to store the output data in Amazon S3, then used an EventBridge rule based on an End Flow Run Report event (which is an event which is published when a flow run is complete) to trigger a load into Amazon Redshift using a COPY statement. The following Diagram 4 shows this workflow.

By using Amazon S3 as an intermediate data store, we gave ourselves greater control over how the data was processed when it was loaded into Amazon Redshift, when compared with loading the data directly to the data warehouse using Amazon AppFlow.

Image 4: Using Amazon AppFlow to integrate external data

Diagram 4: Using Amazon AppFlow to integrate external data to Amazon S3 and copy to Amazon Redshift

Pattern 4: Reverse ETL

Although most of our workflows involve data being brought into the data warehouse from external sources, in some cases we needed the data to be exported to external systems instead. This way, we could run SQL queries with complex logic drawing on multiple data sources and use this logic to support operational requirements, such as identifying which groups of students should receive specific communications.

In this flow, shown in the following Diagram 5, we start by running an UNLOAD statement in Amazon Redshift to unload the relevant data to files in Amazon S3. From here, each file is processed by an AWS Lambda function, which performs any necessary transformations and sends the data to the external application through one or more API calls.

Image 5: Reverse ETL workflow, sending data back out to external data sources

Diagram 5: Reverse ETL workflow, sending data back out to external data sources

Outcomes

The re-architecture and migration process took 5 months to complete, from the initial concept to the successful decommissioning of the previous third-party tool. Most of the architectural effort was completed by a single full-time employee, with others on the team primarily assisting with the migration of pipelines to the new architecture.

We achieved significant cost reductions, with final expenses on AWS native services representing only a small percentage of projected costs compared to continuing with the third-party ETL tool. Moving to a code-based approach also gave us greater visibility of our pipelines and made the process of maintaining them quicker and easier. Overall, the transition was seamless for our end users, who were able to view the same data and dashboards both during and after the migration, with minimal disruption along the way.

Conclusion

By using the scalability and cost-effectiveness of AWS services, we were able to optimize our data pipelines, reduce our operational costs, and improve our agility.

Pete Allen, an analytics engineer from Open Universities Australia, says, “Modernizing our data architecture with AWS has been transformative. Transitioning from an external platform to an in-house, code-based analytics stack has vastly improved our scalability, flexibility, and performance. With AWS, we can now process and analyze data with much faster turnaround, lower costs, and higher availability, enabling rapid development and deployment of data solutions, leading to deeper insights and better business decisions.”

Additional resources


About the Authors

Michael Davies is a Data Engineer at OUA. He has extensive experience within the education industry, with a particular focus on building robust and efficient data architecture and pipelines.

Emma Arrigo is a Solutions Architect at AWS, focusing on education customers across Australia. She specializes in leveraging cloud technology and machine learning to address complex business challenges in the education sector. Emma’s passion for data extends beyond her professional life, as evidenced by her dog named Data.

Hybrid big data analytics with Amazon EMR on AWS Outposts

Post Syndicated from Shoukat Ghouse original https://aws.amazon.com/blogs/big-data/hybrid-big-data-analytics-with-amazon-emr-on-aws-outposts/

Businesses require powerful and flexible tools to manage and analyze vast amounts of information. Amazon EMR has long been the leading solution for processing big data in the cloud. Amazon EMR is the industry-leading big data solution for petabyte-scale data processing, interactive analytics, and machine learning using over 20 open source frameworks such as Apache Hadoop, Hive, and Apache Spark. However, data residency requirements, latency issues, and hybrid architecture needs often challenge purely cloud-based solutions.

Enter Amazon EMR on AWS Outposts—a groundbreaking extension that brings the power of Amazon EMR directly to your on-premises environments. This innovative service merges the scalability, performance (the Amazon EMR runtime for Apache Spark is 4.5 times more performant than Apache Spark 3.5.1), and ease of Amazon EMR with the control and proximity of your data center, empowering enterprises to meet stringent regulatory and operational requirements while unlocking new data processing possibilities.

In this post, we dive into the transformative features of EMR on Outposts, showcasing its flexibility as a native hybrid data analytics service that allows seamless data access and processing both on premises and in the cloud. We also explore how it integrates smoothly with your existing IT infrastructure, providing the flexibility to keep your data where it best fits your needs while performing computations entirely on premises. We examine a hybrid setup where sensitive data remains locally in Amazon S3 on Outposts and public data in an AWS Regional Amazon Simple Storage Service bucket. This configuration allows you to augment your sensitive on-premises data with cloud data while making sure all data processing and compute runs on-premises in AWS Outposts Racks.

Solution overview

Consider a fictional company named Oktank Finance. Oktank aims to build a centralized data lake to store vast amounts of structured and unstructured data, enabling unified access and supporting advanced analytics and big data processing for data-driven insights and innovation. Additionally, Oktank must comply with data residency requirements, making sure that confidential data is stored and processed strictly on premises. Oktank also needs to enrich their datasets with non-confidential and public market data stored in the cloud on Amazon S3, which means they should be able to join datasets across their on-premises and cloud data stores.

Traditionally, Oktank’s big data platforms tightly coupled compute and storage resources, creating an inflexible system where decommissioning compute nodes could lead to data loss. To avoid this situation, Oktank aims to decouple compute from storage, allowing them to scale down compute nodes and repurpose them for other workloads without compromising data integrity and accessibility.

To meet these requirements, Oktank decides to adopt Amazon EMR on Outposts as their big data analytics platform and Amazon S3 on Outposts as their on-premises data store for their data lake. With EMR on Outposts, Oktank can make sure that all compute occurs on premises within their Outposts rack while still being able to query and join the public data stored in Amazon S3 with their confidential data stored in S3 on Outposts, using the same unified data APIs. For data processing, Oktank can choose from a wide variety of applications available on Amazon EMR. In this post, we use Spark as the data processing framework.

This approach makes sure that all data processing and analytics are performed locally within their on-premises environment, allowing Oktank to maintain compliance with data privacy and regulatory requirements. Simultaneously, by avoiding the need to replicate public data to their on-premises data centers, Oktank reduces storage costs and simplifies their end-to-end data pipelines by eliminating additional data movement jobs.

The following diagram illustrates the high-level solution architecture.

As explained earlier, the S3 on Outposts bucket in the architecture holds Oktank’s sensitive data, which stays on the Outpost in Oktank’s data center while the Regional S3 bucket holds the non-sensitive data.

In this post, to achieve high network performance from the Outpost to the Regional S3 bucket and vice-versa, we also use AWS Direct Connect with a virtual private gateway. This is especially beneficial when you need higher query throughput to the Regional S3 bucket by making sure the traffic is routed through your own dedicated network channel to AWS.

The solution involves deploying an EMR cluster on an Outposts rack. A service link connects AWS Outposts to a Region. The service link is a necessary connection between your Outposts and the Region (or home Region). It allows for the management of the Outposts and the exchange of traffic to and from the Region.

You can also access Regional S3 buckets using this service link. However, in this post, we employ an alternate option to enable the EMR cluster to privately access the Regional S3 bucket through the local gateway. This helps optimize data access from the Regional S3 bucket as traffic is routed through Direct Connect.

To enable the EMR cluster to access Amazon S3 privately over Direct Connect, a route is configured in the Outposts subnet (marked as 2 in the architecture diagram) to direct Amazon S3 traffic through the local gateway. Upon reaching the local gateway, the traffic is routed over Direct Connect (private virtual interface) to a virtual private gateway in the Region. The second VPC (5 in diagram), which includes the S3 interface endpoint, is connected to this virtual private gateway. A route is then added to make sure that traffic can return to the EMR cluster. This setup provides more efficient, higher-bandwidth communication between the EMR cluster and Regional S3 buckets.

For big data processing, we use Amazon EMR. Amazon EMR supports access to local S3 on Outposts with the Apache Hadoop S3A connector from Amazon EMR version 7.0.0 onwards. EMR File System (EMRFS) with S3 on Outposts is not supported. We use EMR Studio notebooks for running interactive queries on the data. We also submit Spark jobs as a step on the EMR cluster. We also use the AWS Glue Data Catalog as the external Hive compatible metastore, which serves as the central technical metadata catalog. The Data Catalog is a centralized metadata repository for all your data assets across various data sources. It provides a unified interface to store and query information about data formats, schemas, and sources. Additionally, we use AWS Lake Formation for access controls on the AWS Glue table. You still need to control the raw files access on the S3 on Outposts bucket with AWS Identity and Access Management (IAM) permissions in this architecture. At the time of writing, Lake Formation can’t directly manage access to data on the S3 on Outposts bucket. Access to the actual data files stored in the S3 on Outposts bucket is managed with IAM permissions.

In the following sections, you will implement this architecture for Oktank. We focus on a specific use case for Oktank Finance, where they maintain sensitive customer stockholding data in a local S3 on Outposts bucket. Additionally, they have publicly available stock details stored in a Regional S3 bucket. Their goal is to explore both the datasets within their on-premises Outpost setup. Additionally, they need to enrich the customer stock holdings data by combining it with the publicly available stock details data.

First, we explore how to access both datasets using an EMR cluster. Then, we demonstrate the process of performing joins between the local and public data. We also demonstrate how to use Lake Formation to effectively manage permissions for these tables. We explore two primary scenarios throughout this walkthrough. In the interactive use case, we demonstrate how users can connect to the EMR cluster and run queries interactively using EMR Studio notebooks. This approach allows for real-time data exploration and analysis. Additionally, we show you how to submit batch jobs to Amazon EMR using EMR steps for automated, scheduled data processing. This method is ideal for recurring tasks or large-scale data transformations.

Prerequisites

Complete the following prerequisite steps:

  1. Have an AWS account and a role with administrator access. If you don’t have an account, you can create one.
  2. Have an Outposts rack installed and running.
  3. Create an EC2 key pair. This allows you to connect to the EMR cluster nodes even if Regional connectivity is lost.
  4. Set up Direct Connect. This is required only if you want to deploy the second AWS CloudFormation template as explained in the following section.

Deploy the CloudFormation stacks

In this post, we’ve divided the setup into four CloudFormation templates, each responsible for provisioning a specific component of the architecture. The templates come with default parameters, which you may need to adjust based on your specific configuration requirements.

Stack1 provisions the network infrastructure on Outposts. It also creates the S3 on Outposts bucket and Regional S3 bucket. It copies the sample data to the buckets to simulate the data setup for Oktank. Confidential data for customer stock holdings is copied to the S3 on Outposts bucket, and non-confidential data for stock details is copied to the Regional S3 bucket.

Stack2 provisions the infrastructure to connect to the Regional S3 bucket privately using Direct Connect. It establishes a VPC with private connectivity to both the regional S3 bucket and the Outposts subnet. It also creates an Amazon S3 VPC interface endpoint to allow private access to Amazon S3. It establishes a virtual private gateway for connectivity between the VPC and Outposts subnet. Lastly, it configures a private Amazon Route 53 hosted zone for Amazon S3, enabling private DNS resolution for S3 endpoints within the VPC. You can skip deploying this stack if you don’t need to route traffic using Direct Connect.

Stack3 provisions the EMR cluster infrastructure, AWS Glue database, and AWS Glue tables. The stack creates an AWS Glue database named oktank_outpostblog_temp and three tables under it: stock_details, stockholdings_info, and stockholdings_info_detailed. The table stock_details contains public information for the stocks, and the data location of this table points to the Regional S3 bucket. The tables stockholdings_info and stockholdings_info_detailed contain confidential information, and their data location is in the S3 on Outposts bucket. It also creates a runtime role named outpostblog-runtimeRole1. A runtime role is an IAM role that you associate with an EMR step, and jobs use this role to access AWS resources. With runtime roles for EMR steps, you can specify different IAM roles for the Spark and the Hive jobs, thereby scoping down access at a job level. This allows you to simplify access controls on a single EMR cluster that is shared between multiple tenants, wherein each tenant can be isolated using IAM roles. This stack also grants the required permissions on the runtime role to grant access on the Regional S3 bucket and the S3 on Outposts bucket. The EMR cluster uses a bootstrap action that runs a script to copy sample data to the S3 on Outposts bucket and the Regional S3 bucket for the two tables.

Stack4 provisions the EMR Studio. We will connect to EMR Studio notebook and interact with the data stored across S3 on Outposts and the Regional S3 bucket. This stack outputs the EMR Studio URL, which you can use to connect to EMR Studio.

Run the preceding CloudFormation stacks in sequence with an admin role to create the solution resources.

Access the data and join tables

To verify the solution, complete the following steps:

  1. On the AWS CloudFormation console, navigate to the Outputs tab of Stack4, which deployed the EMR Studio, and choose the EMR Studio URL.

This will open EMR Studio in a new window.

  1. Create a workspace and use the default options.

The workspace will launch in a new tab.

  1. Connect to the EMR cluster using the runtime role (outpostblog-runtimeRole1).

You are now connected to the EMR cluster.

  1. Choose the File Browser tab and open the notebook while choosing the kernel as PySpark.
    File browser tab
  2. Run the following query in the notebook to read from the stock details table. This table points to public data stored in the Regional S3 bucket.
    spark.sql("select * from oktank_outpostblog_temp.stock_details").show(5)

    Public data stored

  3. Run the following query to read from the confidential data stored in the local S3 on Outposts bucket:
    spark.sql("select * from oktank_outpostblog_temp.stockholdings_info").show(5)

    Confidential data

As highlighted earlier, one of the requirements for Oktank is to enrich the preceding data with data from the Regional S3 bucket.

  1. Run the following query to join the preceding two tables:
    spark.sql("select customerid,sharesheld,purchasedate, a.stockid, b.stockname,b.category,b.currentprice from oktank_outpostblog_temp.stockholdings_info a inner join oktank_outpostblog_temp.stock_details b on a.stockid=b.stockid order by customerid").show(10)

    S3 on Outposts

Control access to tables using Lake Formation

In this post, we also showcase how you can control access to the tables using Lake Formation. To demonstrate, let’s block access to RuntimeRole1 on the stockholdings_info table.

  1. On the Lake Formation console, choose Tables in the navigation pane.
  2. Select the table stockholdings_info and on the Actions menu, choose View to view the current access permissions on this table.
    AWS Lake Formation
  3. Select IAMAllowedPrincipals from the list of principals and choose Revoke to revoke the permission.
    Revoke permissions
  4. Go back to the EMR Studio notebook and rerun the earlier query.
    Data access query fails

Oktank’s data access query fails because Lake Formation has denied permission to the runtime role; you will need to adjust the permissions.

  1. To resolve this issue, return to the Lake Formation console, select the stockholdings_info table, and on the Actions menu, choose Grant.
  2. Assign the necessary permissions to the runtime role to make sure it can access the table.
    Grant permission
  3. Select IAM users and roles and choose the runtime role (outpostblog-runtimeRole1).
    Grant data lake permissions
  4. Choose the table stockholdings_info from the list of tables and for Table permissions, select Select.
    Table permissions
  5. Select All data access and choose Grant.
    Data permissions
  6. Go back to the notebook and rerun the query.
    Rerun the query

The query now succeeds because we granted access to the runtime role connected to the EMR cluster through the EMR Studio notebook. This demonstrates how Lake Formation allows you to manage permissions on your Data Catalog tables.

The previous steps only restrict access to the table in the catalog, not to the actual data files stored in the S3 on Outposts bucket. To control access to these data files, you need to use IAM permissions. As mentioned earlier, Stack3 in this post handles the IAM permissions for the data. For access control on the Regional S3 bucket with Lake Formation, you don’t need to specifically provide IAM permissions on the specific S3 bucket to the roles. Lake Formation manages the Regional S3 bucket access controls for runtime roles. Refer to Introducing runtime roles for Amazon EMR steps: Use IAM roles and AWS Lake Formation for access control with Amazon EMR for detailed guidance on managing access to a Regional S3 bucket with Lake Formation and EMR runtime roles.

Submit a batch job

Next, let’s submit a batch job as an EMR step on the EMR cluster. Before we do that, let’s confirm there is currently no data in the table stockholdings_info_detailed. Run the following query in the notebook:

spark.sql("select * from oktank_outpostblog_temp.stockholdings_info_detailed").show(10)

Submit a batch job
You will not see any data in this table. You can now detach the notebook from the cluster.
You will now insert data in this table using a batch job submitted as an EMR step.

  1. On the EMR console, navigate to the cluster EMROutpostBlog and submit a step.
  2. Choose Spark Application for Type.
  3. Select the py script from the scripts folder in your S3 bucket created by the CloudFormation template.
  4. For Permissions, choose the runtime role (outpostblog-RuntimeRole1).
  5. Choose Add step to submit the job.

Wait for the job to complete. The job inserted data into the stockholdings_info_detailed table. You can rerun the earlier query in the notebook to verify the data:

spark.sql("select * from oktank_outpostblog_temp.stockholdings_info_detailed").show(10)

Verify the data

Clean up

To avoid incurring further charges, delete the CloudFormation stacks.

  1. Before deleting Stack4, run the following shell command (with the %%sh magic command) in the EMR Studio notebook to delete the objects from the S3 on Outposts bucket:
    aws s3api delete-objects --bucket <replace with value of key S3OutpostBucketAccessPointAlias1 from stack 3 output> --delete "$(aws s3api list-object-versions --bucket <replace with value of key S3OutpostBucketAccessPointAlias1 from stack 3 output> --output=json | jq '{Objects: [.Versions[]|{Key:.Key,VersionId:.VersionId}], Quiet: true}')"

    Delete the objects from the S3 on Outposts bucket

  2. Next, manually delete the EMR workspace from the EMR Studio.
  3. You can now delete the stacks, starting with Stack4, Stack3, Stack2, and finally Stack1.

Conclusion

In this post, we demonstrated how to use Amazon EMR on Outposts as a managed big data processing service in your on-premises setup. We explored how you can set up the cluster to access data stored in an S3 on Outposts bucket on premises and also efficiently access data in the Regional S3 bucket with private networking. We also explored Glue Data Catalog as a serverless external Hive metastore and managed access control to the catalog tables using Lake Formation. We accessed the data interactively using EMR Studio notebooks and processed it as a batch job using EMR steps.

To learn more, visit Amazon EMR on AWS Outposts.

For further reading, refer to the following resources:


About the Authors

Shoukat Ghouse is a Senior Big Data Specialist Solutions Architect at AWS. He helps customers around the world build robust, efficient and scalable data platforms on AWS leveraging AWS analytics services like AWS Glue, AWS Lake Formation, Amazon Athena and Amazon EMR.

Fernando Galves is an Outpost Solutions Architect at AWS, specializing in networking, security, and hybrid cloud architectures. He helps customers design and implement secure hybrid environments using AWS Outposts, focusing on complex networking solutions and seamless integration between on-premises and cloud infrastructure.

How MuleSoft achieved cloud excellence through an event-driven Amazon Redshift lakehouse architecture

Post Syndicated from Sean Zou original https://aws.amazon.com/blogs/big-data/how-mulesoft-achieved-cloud-excellence-through-an-event-driven-amazon-redshift-lakehouse-architecture/

This post is cowritten with Sean Zou, Terry Quan and Audrey Yuan from MuleSoft.

In our previous thought leadership blog post Why a Cloud Operating Model we defined a COE Framework and showed why MuleSoft implemented it and the benefits they received from it. In this post, we’ll dive into the technical implementation describing how MuleSoft used Amazon EventBridge, Amazon Redshift, Amazon Redshift Spectrum, Amazon S3, & AWS Glue to implement it.

Solution overview

MuleSoft’s solution was to build a lakehouse built on top of AWS services, illustrated in the following diagram, supporting a portal. To provide near real-time analytics we used an event-driven strategy that which would trigger AWS Glue jobs an refresh materialized views.  We also implemented a layered approach that included collection, preparation, and enrichment making it straightforward to identify areas that affect data accuracy.

For MuleSoft’s lakehouse end-to-end solution, the following phases are key:

  • Preparation phase
  • Enrichment phase
  • Action phase

In the following sections, we discuss these phases in more detail.

Preparation phase

Using the COE Framework, we engaged with the stakeholders in the preparation phase to determine the business goals and identify the data sources to ingest. Examples of data sources were cloud assets inventory, AWS Cost and Usage Reports, and AWS Trusted Advisor data. The ingested data is processed in the lakehouse to implement the Well-Architected pillars, utilization, security, and compliance status checks and measures.

How you configure the CUR data and the Trusted Advisor data to land into S3?

The configuration process involves multiple components for both CUR and Trusted Advisor data storage. For CUR setup, customers need to configure an S3 bucket where the CUR report will be delivered, either by selecting an existing bucket or creating a new one. The S3 bucket requires a policy to be applied and customers must specify an S3 path prefix which creates a subfolder for CUR file delivery .

Trusted Advisor data is configured to use Kinesis Firehose to deliver customer summary data to the Support Data lake S3 bucket .The data ingestion process uses firehose buffer parameters (1MB buffer size and 60-second buffer time) to manage data flow to the S3 bucket .

The Trusted Advisor data is stored in JSON and GZIP format, following a specific folder structure with hourly partitions using the “YYYY-MM-DD-HH” format .

The S3 partition structure for Trusted Advisor customer summary data includes separate paths for success and error data, and the data is encrypted using a KMS key specific to Trusted Advisor data .

MuleSoft used AWS managed services and data ingestion tools to pull from multiple data sources and that can support customizations. Cloudquery is used tool to gather cloud infrastructure information, which can connect many infrastructure data sources out of the box and land it into an Amazon S3 bucket. The MuleSoft Anypoint Platform provides an integration layer to integrate infrastructure tools, accommodating many data sources like on-premise, SaaS, and commercial off-the-shelf (COTS) software. Cloud Custodian  was used for its capability of managing cloud resources and auto-remediation with customizations.

Enrichment phase

The enrichment phase includes ingesting raw data aligning with our business goals into the lakehouse through our pipelines, and consolidating the data to create a single pane of glass.

The pipelines adopt the event-driven architecture consisting of EventBridge, Amazon Simple Queue Service (Amazon SQS), and Amazon S3 Event Notifications to provide near real-time data for analysis. When new data arrives in the source bucket, new object creation is captured by the EventBridge rule, which invokes the AWS Glue workflow, consisting of an AWS Glue crawler and AWS Glue extract, transform, and load (ETL) jobs. We also configured S3 Event Notifications to send messages to the SQS queue to make sure the pipeline will only process the new data.

The AWS Glue ETL job cleanses and standardizes the data, so that it’s ready to be analyzed using Amazon Redshift. To tackle data with complex structures, additional processing is performed to flatten the nested data formats into a relational model. The flattening step also extracts the tags of AWS assets out of the nested JSON objects and pivots them into individual columns, enabling tagging enforcement controls and ownership attribution.  The ownership attribution of the infrastructure data provides accountability and holds teams responsible for the costs, utilization, security, compliance, and remediation of their cloud assets.  One important tag is asset ownership which is from the tags extracted from the flattening step, this data can be attributed to the corresponding owners by SQL scripts.

When the workflow is complete, the raw data from different sources and with various structures is now  centralized in the data warehouse.  From there, disjointed data with different purposes is ready to be consolidated and translated into actionable intelligence in the Well-Architected Pillars by coding out the business logic.

 Solutions for the enrichment phase

In the enrichment phase, we faced a number of storage, efficiency, and scalability challenges given the sheer volume of data. We used three techniques (file partitioning, Redshift Spectrum, and materialized views) to address these issues and scale without compromising performance.

File partitioning

MuleSoft’s infrastructure data is stored in folder structure: year, month, day, hour, account, and Region in an S3 bucket, so AWS Glue crawlers are able to automatically identify and add partitions to the tables in the AWS Glue Data Catalog. Partitioning helps improve query performance significantly because it optimizes parallel processing for queries. The amount of data scanned by each query is restricted based on the partition keys, helping reduce overall data transfers, processing time, and computation costs. Although partitioning is an optimization technique that helps improve query efficiency, it’s important to keep in mind two key points while using this technique:

  • The Data Catalog has a maximum cap of 10 million partitions per table
  • Query performance gets compromised as partitions grow rapidly

Therefore, balancing the number of partitions in the Data Catalog tables and query efficiency is essential. We decided on a data retention policy of 3 months and configured a lifecycle rule to expire any data older than that.

Our event-driven architecture–AWS Eventbridge event is invoked when objects are put into or removed from an S3 bucket, event messages are published to the SQS queue using S3 Event Notifications, which invokes an AWS Glue crawler to either add new partitions or removes old partitions from the Data Catalog based on the messages handling the partition cleanup.

Amazon Redshift and concurrency scaling

MuleSoft uses Amazon Redshift to query the data in S3 because it provides large scale compute and minimized data redundancy. MuleSoft also used Amazon Redshift concurrency scaling to run concurrent queries with consistently fast query performance. Amazon Redshift automatically added query processing power in seconds to process a high number of concurrent queries without any delays.

Materialized views

Another technique we used is Amazon Redshift materialized views. Materialized views store preset query results that future similar queries can use, so many computation steps can be skipped. Therefore, relevant data can be accessed efficiently, which leads to query optimization. Additionally, materialized views can be automatically and incrementally refreshed. Therefore, we can achieve a single pane of glass in our cloud infrastructure with the most up-to-date projections, trends, and actionable insights to our organization with improved query performance.

Amazon Redshift Materialized Views (MVs) are used extensively for reporting in MuleSoft’s Cloud Central portal, but if users needed to drill down into a granular view they could reference external tables.

Mulesoft is currently manually refreshing the materialized views through the event-driven architecture, but is evaluating a switch to automatic refresh.

Action phase

Using materialized views in Amazon Redshift, we developed a self-serve Cloud Central portal in Tableau to provide a display portal for each team, engineer, and manager offering guidance and recommendations to help them operate in a way that aligns with the organization’s requirements, standards, and budget. Managers are empowered with monitoring and decision-making information for their teams. Engineers are able to identify and tag assets with missing mandatory tagging information, as well as remediate non-compliant resources. A key feature of the portal is personalization, meaning that the portal is enabled to populate visualizations and analysis based on the relevant data associated with a manager’s or engineer’s login information.

Cloud Central also helps engineering teams improve their cloud maturity in the six Well-Architecture pillars: operational excellence, security, reliability, performance efficiency, cost optimization, and sustainability. The team proved out the “art of possible” by poc’ing Amazon Q to assist with 100 and 200 Well-Architected pillar inquiries and how to’s. The following screenshot illustrates the MuleSoft implementation of the portal, Cloud Central. Other companies will design portals that are more bespoke to their own use cases and requirements.

Conclusion

The technical and business impact of MuleSoft’s COE Framework enables an optimization strategy and a cloud usage show back approach which helps MuleSoft continue to grow with a scalable and sustainable cloud infrastructure. The framework also drives continual maturity and benefits in cloud infrastructure centered around the six Well-Architecture pillars shown in the following figure.

The framework helps organizations with expanded public cloud infrastructure achieve their business goals guided by the Well-Architected benefits powered by an event-driven architecture.

The event-driven Amazon Redshift lakehouse architecture solution offers near real-time actionable insights on decision-making, control, and accountability. The event-driven architecutre can be distilled into modules which can be added or deleted depending on your technical/business goals.

The team is exploring new ways to lower the total cost of ownership. They are evaluating Amazon Redshift Serverless for transient database workloads as well as exploring Amazon DataZone to aggregate and correlate data sources into a data catalog to share among teams, applications, and lines of businesses in a democratized way. We can increase visibility, productivity, and scalability with a well-thought-out lakehouse solution.

We invite organizations and enterprises to take a holistic approach to understand their cloud resources, infrastructure, and applications. You can enable and educate your teams through a single pane of glass, while running on a data modernization lakehouse applying Well-Architected concepts, best practices, and cloud-centric principles. This solution can ultimately enable near real-time streaming, leveling up a COE Framework well into the future.


About the Authors

Sean Zou is a Cloud Operations leader with MuleSoft at Salesforce. Sean has been involved in many aspects of MuleSoft’s Cloud Operations, and helped drive MuleSoft’s cloud infrastructure to scale more than tenfold in 7 years. He built the Oversight Engineering function at MuleSoft from scratch.

Terry Quan focuses on FinOps issues. He works on MuleSoft Engineering on cloud computing budgets and forecasting, cost reduction efforts, costs-to-serve, and coordinates with Salesforce Finance. Terry is a FinOps Practitioner and Professional Certified.

Audrey Yuan is a Software Engineer with MuleSoft at Salesforce. Audrey works on data lakehouse solutions to help drive cloud maturity across the six pillars of the Well-Architected Framework.

Rueben Jimenez is a Senior Solutions Architect at AWS, designing and implementing complex data analytics, AI/ML, and cloud infrastructure solutions.

Avijit Goswami is a Principal Solutions Architect at AWS specialized in data and analytics. He supports AWS strategic customers in building high-performing, secure, and scalable data lake solutions on AWS using AWS managed services and open source solutions. Outside of his work, Avijit likes to travel, hike, watch sports, and listen to music.

Top Architecture Blog Posts of 2024

Post Syndicated from Andrea Courtright original https://aws.amazon.com/blogs/architecture/top-architecture-blog-posts-of-2024/

Well, it’s been another historic year! We’ve watched in awe as the use of real-world generative AI has changed the tech landscape, and while we at the Architecture Blog happily participated, we also made every effort to stay true to our channel’s original scope, and your readership this last year has proven that decision was the right one.

AI/ML carries itself in the top posts this year, but we’re also happy to see that foundational topics like resiliency and cost optimization are still of great interest to our audience.

(By the way, if you were hoping for more AI/ML content, head on over to our sister channel, the AWS Machine Learning Blog!).

Without further ado, here are our top posts from 2024!

#10 Deploy Stable Diffusion ComfyUI on AWS elastically and efficiently

This post helps you get started using ComfyUI, and was so successful that we followed it up later in the year with How to build custom nodes workflow with ComfyUI on EKS!

Architecture for deploying stable diffusion on ComfyUI

Figure 1. Architecture for deploying stable diffusion on ComfyUI

#9 Let’s Architect! Designing Well-Architected systems

In keeping with Let’s Architect! series, we have our first of three favorites for the year. This set of resources helps you apply Well-Architected standards in practice.

Let's Architect

Figure 2. Let’s Architect

#8 Let’s Architect! Learn About Machine Learning on AWS

As I said, Let’s Architect! has a winning series, and they’ve got a finger on the pulse of the tech world. This post about machine learning showcases some of the most exciting things happening at AWS.

Let's Architect

Figure 3. Let’s Architect

If you’re more interested in generative AI, you can also take a look at another post from 2024: Let’s Architect! GenAI

#7 Creating an organizational multi-Region failover strategy

Preparedness is another common theme in this year’s favorites. Michael, John, and Saurabh are well-versed in multi-Region architecture, and they’re here to share some strategies to contain failure impact.

When the application experiences an impairment using S3 resources in the primary Region, it fails over to use an S3 bucket in the secondary Region.

Figure 4. When the application experiences an impairment using S3 resources in the primary Region, it fails over to use an S3 bucket in the secondary Region.

#6 Building a three-tier architecture on a budget

Let’s talk cost optimization. This post about a three-tier architecture that relies on the AWS Free Tier is a must-read for anyone looking for tips to help them avoid unnecessary costs (and that’s everyone).

Example of a three-tier architecture on AWS

Figure 5. Example of a three-tier architecture on AWS

#5 Announcing updates to the AWS Well-Architected Framework guidance

As usual, Haleh & team are pros at making sure the Well-Architected Framework is current and relevant. Take a look at the enhanced and expanded guidance in all six pillars.

Well-Architected logo

Figure 6. Well-Architected logo

#4 Let’s Architect! Serverless developer experience in AWS

One more winning post from Luca, Federica, Vittorio, and Zamira! This collection of developer resources includes new ideas in AWS Lambda, Amazon Q Developer, and Amazon DynamoDB.

Let's Architect

Figure 7. Let’s Architect

#3 London Stock Exchange Group uses chaos engineering on AWS to improve resilience

This post from April 1 was not an April Fool’s joke! See how LSEG designed failure scenarios to test their resilience and observability.

Chaos engineering pattern for hybrid architecture (3-tier application)

Figure 8. Chaos engineering pattern for hybrid architecture (3-tier application)

#2 Achieving Frugal Architecture using the AWS Well-Architected Framework Guidance

Frugality AND Well-Architected? What a winning combo! This post, inspired by the 2023 re:Invent keynote, outlines the seven laws of Frugal Architecture.

Well-Architected logo

Figure 9. Well-Architected logo

#1 How an insurance company implements disaster recovery of 3-tier applications

And finally, our number one post of the year! Amit and Luiz showcase a customer solution with real-world applications that builds on the guidelines of other posts in this list! Well done!

The Pilot Light scenario for a 3-tier application that has application servers and a database deployed in two Regions

Figure 10. The Pilot Light scenario for a 3-tier application that has application servers and a database deployed in two Regions

Thank you!

As always, thanks to our contributors for their dedication and desire to share, and to you, our readers! We would be nothing with you. Literally.

For other top post lists, see our Top 10 and Top 5 posts from previous years.

Accelerate queries on Apache Iceberg tables through AWS Glue auto compaction

Post Syndicated from Navnit Shukla original https://aws.amazon.com/blogs/big-data/accelerate-queries-on-apache-iceberg-tables-through-aws-glue-auto-compaction/

Data lakes were originally designed to store large volumes of raw, unstructured, or semi-structured data at a low cost, primarily serving big data and analytics use cases. Over time, as organizations began to explore broader applications, data lakes have become essential for various data-driven processes beyond just reporting and analytics. Today, they play a critical role in syncing with customer applications, enabling the ability to manage concurrent data operations while maintaining the integrity and consistency of information. This shift includes not only storing batch data but also ingesting and processing near real-time data streams, allowing businesses to merge historical insights with live data to power more responsive and adaptive decision-making. However, this new data lake architecture brings challenges around managing transactional support and handling the influx of small files generated by real-time data streams. Traditionally, customers addressed these challenges by performing complex extract, transform, and load (ETL) processes, which often led to data duplication and increased complexity in data pipelines. Additionally, to cope with the proliferation of small files, organizations had to develop custom mechanisms to compact and merge these files, leading to the creation and maintenance of bespoke solutions that were difficult to scale and manage. As data lakes increasingly handle sensitive business data and transactional workloads, maintaining strong data quality, governance, and compliance becomes vital to maintaining trust and regulatory alignment.

To simplify these challenges, organizations have adopted open table formats (OTFs) like Apache Iceberg, which provide built-in transactional capabilities and mechanisms for compaction. OTFs, such as Iceberg, address key limitations in traditional data lakes by offering features like ACID transactions, which maintain data consistency across concurrent operations, and compaction, which helps manage the issue of small files by merging them efficiently. By using features like Iceberg’s compaction, OTFs streamline maintenance, making it straightforward to manage object and metadata versioning at scale. However, although OTFs reduce the complexity of maintaining efficient tables, they still require some regular maintenance to make sure tables remain in an optimal state.

In this post, we explore new features of the AWS Glue Data Catalog, which now supports improved automatic compaction of Iceberg tables for streaming data, making it straightforward for you to keep your transactional data lakes consistently performant. Enabling automatic compaction on Iceberg tables reduces metadata overhead on your Iceberg tables and improves query performance. Many customers have streaming data continuously ingested in Iceberg tables, resulting in a large number of delete files that track changes in data files. With this new feature, as you enable the Data Catalog optimizer. It constantly monitors table partitions and runs the compaction process for both data and delta or delete files, and it regularly commits partial progress. The Data Catalog also now supports heavily nested complex data and supports schema evolution as you reorder or rename columns.

Automatic compaction with AWS Glue

Automatic compaction in the Data Catalog makes sure your Iceberg tables are always in optimal condition. The data compaction optimizer continuously monitors table partitions and invokes the compaction process when specific thresholds for the number of files and file sizes are met. For example, based on the Iceberg table configuration of the target file size, the compaction process will start and continue if the table or any of the partitions within the table have more than the default configuration (for example 100 files), each smaller than 75% of the target file size.

Iceberg supports two table modes: Merge-on-Read (MoR) and Copy-on-Write (CoW). These table modes provide different approaches for handling data updates and play a critical role in how data lakes manage changes and maintain performance:

  • Data compaction on Iceberg CoW – With CoW, any updates or deletes are directly applied to the table files. This means the entire dataset is rewritten when changes are made. Although this provides immediate consistency and simplifies reads (because readers only access the latest snapshot of the data), it can become costly and slow for write-heavy workloads due to the need for frequent rewrites. Announced during AWS re:Invent 2023, this feature focuses on optimizing data storage for Iceberg tables using the CoW mechanism. Compaction in CoW makes sure updates to the data result in new files being created, which are then compacted to improve query performance.
  • Data compaction on Iceberg MoR – Unlike CoW, MoR allows updates to be written separately from the existing dataset, and those changes are only merged when the data is read. This approach is beneficial for write-heavy scenarios because it avoids frequent full table rewrites. However, it can introduce complexity during reads because the system has to merge base and delta files as needed to provide a complete view of the data. MoR compaction, now generally available, allows for efficient handling of streaming data. It makes sure that while data is being continuously ingested, it’s also compacted in a way that optimizes read performance without compromising the ingestion speed.

Whether you are using CoW, MoR, or a hybrid of both, one challenge remains consistent: maintenance around the growing number of small files generated by each transaction. AWS Glue automatic compaction addresses this by making sure your Iceberg tables remain efficient and performant across both table modes.

This post provides a detailed comparison of query performance between auto compacted and non-compacted Iceberg tables. By analyzing key metrics such as query latency and storage efficiency, we demonstrate how the automatic compaction feature optimizes data lakes for better performance and cost savings. This comparison will help guide you in making informed decisions on enhancing your data lake environments.

Solution overview

This blog post explores the performance benefits of the newly launched feature in AWS Glue that supports automatic compaction of Iceberg tables with MoR capabilities. We run two versions of the same architecture: one where the tables are auto compacted, and another without compaction. By comparing both scenarios, this post demonstrates the efficiency, query performance, and cost benefits of auto compacted tables vs. non-compacted tables in a simulated Internet of Things (IoT) data pipeline.

The following diagram illustrates the solution architecture.

The solution consists of the following components:

  • Amazon Elastic Compute Cloud (Amazon EC2) simulates continuous IoT data streams, sending them to Amazon MSK for processing
  • Amazon Managed Streaming for Apache Kafka (Amazon MSK) ingests and streams data from the IoT simulator for real-time processing
  • Amazon EMR Serverless processes streaming data from Amazon MSK without managing clusters, writing results to the Amazon S3 data lake
  • Amazon Simple Storage Service (Amazon S3) stores data using Iceberg’s MoR format for efficient querying and analysis
  • The Data Catalog manages metadata for the datasets in Amazon S3, enabling organized data discovery and querying through Amazon Athena
  • Amazon Athena queries data from the S3 data lake with two table options:
    • Non-compacted table – Queries raw data from the Iceberg table
    • Compacted table – Queries data optimized by automatic compaction for faster performance.

The data flow consists of the following steps:

  1. The IoT simulator on Amazon EC2 generates continuous data streams.
  2. The data is sent to Amazon MSK, which acts as a streaming table.
  3. EMR Serverless processes streaming data and writes the output to Amazon S3 in Iceberg format.
  4. The Data Catalog manages the metadata for the datasets.
  5. Athena is used to query the data, either directly from the non-compacted table or from the compacted table after auto compaction.

In this post, we guide you through setting up an evaluation environment for AWS Glue Iceberg auto compaction performance using the following GitHub repository. The process involves simulating IoT data ingestion, deduplication, and querying performance using Athena.

Compaction IoT performance test

We simulated IoT data ingestion with over 20 billion events and used MERGE INTO for data deduplication across two time-based partitions, involving heavy partition reads and shuffling. After ingestion, we ran queries in Athena to compare performance between compacted and non-compacted tables using the MoR format. This test aims to have low latency on ingestion but will lead to hundreds of millions of small files.

We use the following table configuration settings:

'write.delete.mode'='merge-on-read'
'write.update.mode'='merge-on-read'
'write.merge.mode'='merge-on-read'
'write.distribution.mode=none'

We use 'write.distribution.mode=none' to lower the latency. However, it will increase the number of Parquet files. For other scenarios, you may want to use hash or range distribution write modes to reduce the file count.

This test makes make append operations because we’re appending new data to the table but we don’t have any delete operations.

The following table shows some metrics of the Athena query performance.


Execution Time (sec) Performance Improvement (%) Data Scanned (GB)
Query employee (without compaction) employeeauto (with compaction) – employee (without compaction) employeeauto (with compaction)
SELECT count(*) FROM "bigdata"."<tablename>" 67.5896 3.8472 94.31% 0 0
SELECT team, name, min(age) AS youngest_age
FROM "bigdata"."<tablename>"
GROUP BY team, name
ORDER BY youngest_age ASC
72.0152 50.4308 29.97% 33.72 32.96
SELECT role, team, avg(age) AS average_age
FROM bigdata."<tablename>"
GROUP BY role, team
ORDER BY average_age DESC
74.1430 37.7676 49.06% 17.24 16.59
SELECT name, age, start_date, role, team
FROM bigdata."<tablename>"
WHERE
CAST(start_date as DATE) > CAST('2023-01-02' as DATE) and
age > 40
ORDER BY start_date DESC
limit 100
70.3376 37.1232 47.22% 105.74 110.32

Because the previous test didn’t perform any delete operations on the table, we conduct a new test involving hundreds of thousands of such operations. We use the previously auto compacted table (employeeauto) as a base, noting that this table uses MoR for all operations.

We run a query that deletes data from each even second on the table:

DELETE FROM iceberg_catalog.bigdata.employeeauto
WHERE start_date BETWEEN 'start' AND 'end'
AND SECOND(start_date) % 2 = 0;

This query runs with table optimizations enabled, using an Amazon EMR Studio notebook. After running the queries, we roll back the table to its previous state for a performance comparison. Iceberg’s time-traveling capabilities allow us to restore the table. We then disable the table optimizations, rerun the delete query, and follow up with Athena queries to analyze performance differences. The following table summarizes our results.


Execution Time (sec) Performance Improvement (%) Data Scanned (GB)
Query employee (without compaction) employeeauto (with compaction) – employee (without compaction) employeeauto (with compaction)
SELECT count(*) FROM "bigdata"."<tablename>" 29.820 8.71 70.77% 0 0
SELECT team, name, min(age) as youngest_age
FROM "bigdata"."<tablename>"
GROUP BY team, name
ORDER BY youngest_age ASC
58.0600 34.1320 41.21% 33.27 19.13
SELECT role, team, avg(age) AS average_age
FROM bigdata."<tablename>"
GROUP BY role, team
ORDER BY average_age DESC
59.2100 31.8492 46.21% 16.75 9.73
SELECT name, age, start_date, role, team
FROM bigdata."<tablename>"
WHERE
CAST(start_date as DATE) > CAST('2023-01-02' as DATE) and
age > 40
ORDER BY start_date DESC
limit 100
68.4650 33.1720 51.55% 112.64 61.18

We analyze the following key metrics:

  • Query runtime – We compared the runtimes between compacted and non-compacted tables using Athena as the query engine and found significant performance improvements with both MoR for ingestion and appends and MoR for delete operations.
  • Data scanned evaluation – We compared compacted and non-compacted tables using Athena as the query engine and observed a reduction in data scanned for most queries. This reduction translates directly into cost savings.

Prerequisites

To set up your own evaluation environment and test the feature, you need the following prerequisites:

  • A virtual private cloud (VPC) with at least two private subnets. For instructions, see Create a VPC.
  • An EC2 instance c5.xlarge using Amazon Linux 2023 running on one of those private subnets where you will launch the data simulator. For the security group, you can use the default for the VPC. For more information, see Get started with Amazon EC2.
  • An AWS Identity and Access Management (IAM) user with the correct permissions to create and configure all the required resources.

Set up Amazon S3 storage

Create an S3 bucket with the following structure:

s3bucket/
/jars
/employee.desc
/warehouse
/checkpoint
/checkpointAuto

Download the descriptor file employee.desc from the GitHub repo and place it in the S3 bucket.

Download the application on the releases page

Get the packaged application from the GitHub repo, then upload the JAR file to the jars directory on the S3 bucket. The warehouse will be where the Iceberg data and metadata will live and checkpoint will be used for the Structured Streaming checkpointing mechanism. Because we use two streaming job runs, one for compacted and one for non-compacted data, we also create a checkpointAuto folder.

Create a Data Catalog database

Create a database in the Data Catalog (for this post, we name our database bigdata). For instructions, see Getting started with the AWS Glue Data Catalog.

Create an EMR Serverless application

Create an EMR Serverless application with the following settings (for instructions, see Getting started with Amazon EMR Serverless):

  • Type: Spark
  • Version: 7.1.0
  • Architecture: x86_64
  • Java Runtime: Java 17
  • Metastore Integration: AWS Glue Data Catalog
  • Logs: Enable Amazon CloudWatch Logs if desired

Configure the network (VPC, subnets, and default security group) to allow the EMR Serverless application to reach the MSK cluster.

Take note of the application-id to use later for launching the jobs.

Create an MSK cluster

Create an MSK cluster on the Amazon MSK console. For more details, see Get started using Amazon MSK.

You need to use custom create with at least two brokers using 3.5.1, Apache Zookeeper mode version, and instance type kafka.m7g.xlarge. Do not use public access; choose two private subnets to deploy it (one broker per subnet or Availability Zone, for a total of two brokers). For the security group, remember that the EMR cluster and the Amazon EC2 based producer will need to reach the cluster and act accordingly. For security, use PLAINTEXT (in production, you should secure access to the cluster). Choose 200 GB as storage size for each broker and do not enable tiered storage. For network security groups, you can choose the default of the VPC.

For the MSK cluster configuration, use the following settings:

auto.create.topics.enable=true
default.replication.factor=2
min.insync.replicas=2
num.io.threads=8
num.network.threads=5
num.partitions=32
num.replica.fetchers=2
replica.lag.time.max.ms=30000
socket.receive.buffer.bytes=102400
socket.request.max.bytes=104857600
socket.send.buffer.bytes=102400
unclean.leader.election.enable=true
zookeeper.session.timeout.ms=18000
compression.type=zstd
log.retention.hours=2
log.retention.bytes=10073741824

Configure the data simulator

Log in to your EC2 instance. Because it’s running on a private subnet, you can use an instance endpoint to connect. To create one, see Connect to your instances using EC2 Instance Connect Endpoint. After you log in, issue the following commands:

sudo yum install java-17-amazon-corretto-devel
wget https://archive.apache.org/dist/kafka/3.5.1/kafka_2.12-3.5.1.tgz
tar xzvf kafka_2.12-3.5.1.tgz

Create Kafka topics

Create two Kafka topics—remember that you need to change the bootstrap server with the corresponding client information. You can get this data from the Amazon MSK console on the details page for your MSK cluster.

cd kafka_2.12-3.5.1/bin/

./kafka-topics.sh --topic protobuf-demo-topic-pure-auto --bootstrap-server kafkaBoostrapString --create
./kafka-topics.sh --topic protobuf-demo-topic-pure --bootstrap-server kafkaBoostrapString –create

Launch job runs

Issue job runs for the non-compacted and auto compacted tables using the following AWS Command Line Interface (AWS CLI) commands. You can use AWS CloudShell to run the commands.

For the non-compacted table, you need to change the s3bucket value as needed and the application-id. You also need an IAM role (execution-role-arn) with the corresponding permissions to access the S3 bucket and to access and write tables on the Data Catalog.

aws emr-serverless start-job-run --application-id application-identifier --name job-run-name --execution-role-arn arn-of-emrserverless-role --mode 'STREAMING' --job-driver '{
"sparkSubmit": {
"entryPoint": "s3://s3bucket/jars/streaming-iceberg-ingest-1.0-SNAPSHOT.jar",
"entryPointArguments": ["true","s3://s3bucket/warehouse","s3://s3bucket/Employee.desc","s3://s3bucket/checkpoint","kafkaBootstrapString","true"],
"sparkSubmitParameters": "--class com.aws.emr.spark.iot.SparkCustomIcebergIngestMoR --conf spark.executor.cores=16 --conf spark.executor.memory=64g --conf spark.driver.cores=4 --conf spark.driver.memory=16g --conf spark.dynamicAllocation.minExecutors=3 --conf spark.jars=/usr/share/aws/iceberg/lib/iceberg-spark3-runtime.jar --conf spark.dynamicAllocation.maxExecutors=5 --conf spark.sql.catalog.glue_catalog.http-client.apache.max-connections=3000 --conf spark.emr-serverless.executor.disk.type=shuffle_optimized --conf spark.emr-serverless.executor.disk=1000G --files s3://s3bucket/Employee.desc --packages org.apache.spark:spark-sql-kafka-0-10_2.12:3.5.1"
}
}'

For the auto compacted table, you need to change the s3bucket value as needed, the application-id, and the kafkaBootstrapString. You also need an IAM role (execution-role-arn) with the corresponding permissions to access the S3 bucket and to access and write tables on the Data Catalog.

aws emr-serverless start-job-run --application-id application-identifier --name job-run-name --execution-role-arn arn-of-emrserverless-role --mode 'STREAMING' --job-driver '{
"sparkSubmit": {
"entryPoint": "s3://s3bucket/jars/streaming-iceberg-ingest-1.0-SNAPSHOT.jar",
"entryPointArguments": ["true","s3://s3bucket/warehouse","/home/hadoop/Employee.desc","s3://s3bucket/checkpointAuto","kafkaBootstrapString","true"],
"sparkSubmitParameters": "--class com.aws.emr.spark.iot.SparkCustomIcebergIngestMoRAuto --conf spark.executor.cores=16 --conf spark.executor.memory=64g --conf spark.driver.cores=4 --conf spark.driver.memory=16g --conf spark.dynamicAllocation.minExecutors=3 --conf spark.jars=/usr/share/aws/iceberg/lib/iceberg-spark3-runtime.jar --conf spark.dynamicAllocation.maxExecutors=5 --conf spark.sql.catalog.glue_catalog.http-client.apache.max-connections=3000 --conf spark.emr-serverless.executor.disk.type=shuffle_optimized --conf spark.emr-serverless.executor.disk=1000G --files s3://s3bucket/Employee.desc --packages org.apache.spark:spark-sql-kafka-0-10_2.12:3.5.1"
}
}'

Enable auto compaction

Enable auto compaction for the employeeauto table in AWS Glue. For instructions, see Enabling compaction optimizer.

Launch the data simulator

Download the JAR file to the EC2 instance and run the producer:

aws s3 cp s3://s3bucket/jars/streaming-iceberg-ingest-1.0-SNAPSHOT.jar .

Now you can start the protocol buffer producers.

For non-compacted tables, use the following commands:

java -cp streaming-iceberg-ingest-1.0-SNAPSHOT.jar 
com.aws.emr.proto.kafka.producer.ProtoProducer kafkaBoostrapString

For auto compacted tables, use the following commands:

java -cp streaming-iceberg-ingest-1.0-SNAPSHOT.jar 
com.aws.emr.proto.kafka.producer.ProtoProducerAuto kafkaBoostrapString

Test the solution in EMR Studio

For the delete test, we use an EMR Studio. For setup instructions, see Set up an EMR Studio. Next, you need to create an EMR Serverless interactive application to run the notebook; refer to Run interactive workloads with EMR Serverless through EMR Studio to create a Workspace.

Open the Workspace, select the interactive EMR Serverless application as the compute option, and attach it.

Download the Jupyter notebook, upload it to your environment, and run the cells using a PySpark kernel to run the test.

Clean up

This evaluation is for high-throughput scenarios and can lead to significant costs. Complete the following steps to clean up your resources:

  1. Stop the Kafka producer EC2 instance.
  2. Cancel the EMR job runs and delete the EMR Serverless application.
  3. Delete the MSK cluster.
  4. Delete the tables and database from the Data Catalog.
  5. Delete the S3 bucket.

Conclusion

The Data Catalog has improved automatic compaction of Iceberg tables for streaming data, making it straightforward for you to keep your transactional data lakes always performant. Enabling automatic compaction on Iceberg tables reduces metadata overhead on your Iceberg tables and improves query performance.

Many customers have streaming data that is continuously ingested in Iceberg tables, resulting in a large set of delete files that track changes in data files. With this new feature, when you enable the Data Catalog optimizer, it constantly monitors table partitions and runs the compaction process for both data and delta or delete files and regularly commits the partial progress. The Data Catalog also has expanded support for heavily nested complex data and supports schema evolution as you reorder or rename columns.

In this post, we assessed the ingestion and query performance of simulated IoT data using AWS Glue Iceberg with auto compaction enabled. Our setup processed over 20 billion events, managing duplicates and late-arriving events, and employed a MoR approach for both ingestion/appends and deletions to evaluate the performance improvement and efficiency.

Overall, AWS Glue Iceberg with auto compaction proves to be a robust solution for managing high-throughput IoT data streams. These enhancements lead to faster data processing, shorter query times, and more efficient resource utilization, all of which are essential for any large-scale data ingestion and analytics pipeline.

For detailed setup instructions, see the GitHub repo.


About the Authors

Navnit Shukla serves as an AWS Specialist Solutions Architect with a focus on Analytics. He possesses a strong enthusiasm for assisting clients in discovering valuable insights from their data. Through his expertise, he constructs innovative solutions that empower businesses to arrive at informed, data-driven choices. Notably, Navnit Shukla is the accomplished author of the book titled Data Wrangling on AWS. He can be reached through LinkedIn.

Angel Conde Manjon is a Sr. PSA Specialist on Data & AI, based in Madrid, and focuses on EMEA South and Israel. He has previously worked on research related to data analytics and artificial intelligence in diverse European research projects. In his current role, Angel helps partners develop businesses centered on data and AI.

Amit Singh currently serves as a Senior Solutions Architect at AWS, specializing in analytics and IoT technologies. With extensive expertise in designing and implementing large-scale distributed systems, Amit is passionate about empowering clients to drive innovation and achieve business transformation through AWS solutions.
Sandeep Adwankar is a Senior Technical Product Manager at AWS. Based in the California Bay Area, he works with customers around the globe to translate business and technical requirements into products that enable customers to improve how they manage, secure, and access data.

Building end-to-end data lineage for one-time and complex queries using Amazon Athena, Amazon Redshift, Amazon Neptune and dbt

Post Syndicated from Nancy Wu original https://aws.amazon.com/blogs/big-data/building-end-to-end-data-lineage-for-one-time-and-complex-queries-using-amazon-athena-amazon-redshift-amazon-neptune-and-dbt/

One-time and complex queries are two common scenarios in enterprise data analytics. One-time queries are flexible and suitable for instant analysis and exploratory research. Complex queries, on the other hand, refer to large-scale data processing and in-depth analysis based on petabyte-level data warehouses in massive data scenarios. These complex queries typically involve data sources from multiple business systems, requiring multilevel nested SQL or associations with numerous tables for highly sophisticated analytical tasks.

However, combining the data lineage of these two query types presents several challenges:

  1. Diversity of data sources
  2. Varying query complexity
  3. Inconsistent granularity in lineage tracking
  4. Different real-time requirements
  5. Difficulties in cross-system integration

Moreover, maintaining the accuracy and completeness of lineage information while providing system performance and scalability are crucial considerations. Addressing these challenges requires a carefully designed architecture and advanced technical solutions.

Amazon Athena offers serverless, flexible SQL analytics for one-time queries, enabling direct querying of Amazon Simple Storage Service (Amazon S3) data for rapid, cost-effective instant analysis. Amazon Redshift, optimized for complex queries, provides high-performance columnar storage and massively parallel processing (MPP) architecture, supporting large-scale data processing and advanced SQL capabilities. Amazon Neptune, as a graph database, is ideal for data lineage analysis, offering efficient relationship traversal and complex graph algorithms to handle large-scale, intricate data lineage relationships. The combination of these three services provides a powerful, comprehensive solution for end-to-end data lineage analysis.

In the context of comprehensive data governance, Amazon DataZone offers organization-wide data lineage visualization using Amazon Web Services (AWS) services, while dbt provides project-level lineage through model analysis and supports cross-project integration between data lakes and warehouses.

In this post, we use dbt for data modeling on both Amazon Athena and Amazon Redshift. dbt on Athena supports real-time queries, while dbt on Amazon Redshift handles complex queries, unifying the development language and significantly reducing the technical learning curve. Using a single dbt modeling language not only simplifies the development process but also automatically generates consistent data lineage information. This approach offers robust adaptability, easily accommodating changes in data structures.

By integrating Amazon Neptune graph database to store and analyze complex lineage relationships, combined with AWS Step Functions and AWS Lambda functions, we achieve a fully automated data lineage generation process. This combination promotes consistency and completeness of lineage data while enhancing the efficiency and scalability of the entire process. The result is a powerful and flexible solution for end-to-end data lineage analysis.

Architecture overview

The experiment’s context involves a customer already using Amazon Athena for one-time queries. To better accommodate massive data processing and complex query scenarios, they aim to adopt a unified data modeling language across different data platforms. This led to the implementation of both Athena on dbt and Amazon Redshift on dbt architectures.

AWS Glue crawler crawls data lake information from Amazon S3, generating a Data Catalog to support dbt on Amazon Athena data modeling. For complex query scenarios, AWS Glue performs extract, transform, and load (ETL) processing, loading data into the petabyte-scale data warehouse, Amazon Redshift. Here, data modeling uses dbt on Amazon Redshift.

Lineage data original files from both parts are loaded into an S3 bucket, providing data support for end-to-end data lineage analysis.

The following image is the architecture diagram for the solution.

Figure 1-Architecture diagram of DBT modeling based on Athena and Redshift

Some important considerations:

This experiment uses the following data dictionary:

Source table Tool Target table
imdb.name_basics DBT/Athena stg_imdb__name_basics
imdb.title_akas DBT/Athena stg_imdb__title_akas
imdb.title_basics DBT/Athena stg_imdb__title_basics
imdb.title_crew DBT/Athena stg_imdb__title_crews
imdb.title_episode DBT/Athena stg_imdb__title_episodes
imdb.title_principals DBT/Athena stg_imdb__title_principals
imdb.title_ratings DBT/Athena stg_imdb__title_ratings
stg_imdb__name_basics DBT/Redshift new_stg_imdb__name_basics
stg_imdb__title_akas DBT/Redshift new_stg_imdb__title_akas
stg_imdb__title_basics DBT/Redshift new_stg_imdb__title_basics
stg_imdb__title_crews DBT/Redshift new_stg_imdb__title_crews
stg_imdb__title_episodes DBT/Redshift new_stg_imdb__title_episodes
stg_imdb__title_principals DBT/Redshift new_stg_imdb__title_principals
stg_imdb__title_ratings DBT/Redshift new_stg_imdb__title_ratings
new_stg_imdb__name_basics DBT/Redshift int_primary_profession_flattened_from_name_basics
new_stg_imdb__name_basics DBT/Redshift int_known_for_titles_flattened_from_name_basics
new_stg_imdb__name_basics DBT/Redshift names
new_stg_imdb__title_akas DBT/Redshift titles
new_stg_imdb__title_basics DBT/Redshift int_genres_flattened_from_title_basics
new_stg_imdb__title_basics DBT/Redshift titles
new_stg_imdb__title_crews DBT/Redshift int_directors_flattened_from_title_crews
new_stg_imdb__title_crews DBT/Redshift int_writers_flattened_from_title_crews
new_stg_imdb__title_episodes DBT/Redshift titles
new_stg_imdb__title_principals DBT/Redshift titles
new_stg_imdb__title_ratings DBT/Redshift titles
int_known_for_titles_flattened_from_name_basics DBT/Redshift titles
int_primary_profession_flattened_from_name_basics DBT/Redshift
int_directors_flattened_from_title_crews DBT/Redshift names
int_genres_flattened_from_title_basics DBT/Redshift genre_titles
int_writers_flattened_from_title_crews DBT/Redshift names
genre_titles DBT/Redshift
names DBT/Redshift
titles DBT/Redshift

The lineage data generated by dbt on Athena includes partial lineage diagrams, as exemplified in the following images. The first image shows the lineage of name_basics in dbt on Athena. The second image shows the lineage of title_crew in dbt on Athena.

Figure 3-Lineage of name_basics in DBT on Athena

Figure 4-Lineage of title_crew in DBT on Athena

The lineage data generated by dbt on Amazon Redshift includes partial lineage diagrams, as illustrated in the following image.

Figure 5-Lineage of name_basics and title_crew in DBT on Redshift

Referring to the data dictionary and screenshots, it’s evident that the complete data lineage information is highly dispersed, spread across 29 lineage diagrams. Understanding the end-to-end comprehensive view requires significant time. In real-world environments, the situation is often more complex, with complete data lineage potentially distributed across hundreds of files. Consequently, integrating a complete end-to-end data lineage diagram becomes crucial and challenging.

This experiment will provide a detailed introduction to processing and merging data lineage files stored in Amazon S3, as illustrated in the following diagram.

Figure 6-Merging data lineage from Athena and Redshift into Neptune

Prerequisites

To perform the solution, you need to have the following prerequisites in place:

  • The Lambda function for preprocessing lineage files must have permissions to access Amazon S3 and Amazon Redshift.
  • The Lambda function for constructing the directed acyclic graph (DAG) must have permissions to access Amazon S3 and Amazon Neptune.

Solution walkthrough

To perform the solution, follow the steps in the next sections.

Preprocess raw lineage data for DAG generation using Lambda functions

Use Lambda to preprocess the raw lineage data generated by dbt, converting it into key-value pair JSON files that are easily understood by Neptune: athena_dbt_lineage_map.json and redshift_dbt_lineage_map.json.

  1. To create a new Lambda function in the Lambda console, enter a Function name, select the Runtime (Python in this example), configure the Architecture and Execution role, then click the “Create function” button.

Figure 7-Basic configuration of athena-data-lineage-process Lambda

  1. Open the created Lambda function and on the Configuration tab, in the navigation pane, select Environment variables and choose your configurations. Using Athena on dbt processing as an example, configure the environment variables as follows (the process for Amazon Redshift on dbt is similar):
    • INPUT_BUCKET: data-lineage-analysis-24-09-22 (replace with the S3 bucket path storing the original Athena on dbt lineage files)
    • INPUT_KEY: athena_manifest.json (the original Athena on dbt lineage file)
    • OUTPUT_BUCKET: data-lineage-analysis-24-09-22 (replace with the S3 bucket path for storing the preprocessed output of Athena on dbt lineage files)
    • OUTPUT_KEY: athena_dbt_lineage_map.json (the output file after preprocessing the original Athena on dbt lineage file)

Figure 8-Environment variable configuration for athena-data-lineage-process-Lambda

  1. On the Code tab, in the lambda_function.py file, enter the preprocessing code for the raw lineage data. Here’s a code reference using Athena on dbt processing as an example (the process for Amazon Redshift on dbt is similar). The preprocessing code for Athena on dbt’s original lineage file is as follows:

The athena_manifest.json, redshift_manifest.json, and other files used in this experiment can be obtained from the Data Lineage Graph Construction GitHub repository.

import json
import boto3
import os

def lambda_handler(event, context):
    # Set up S3 client
    s3 = boto3.client('s3')

    # Get input and output paths from environment variables
    input_bucket = os.environ['INPUT_BUCKET']
    input_key = os.environ['INPUT_KEY']
    output_bucket = os.environ['OUTPUT_BUCKET']
    output_key = os.environ['OUTPUT_KEY']

    # Define helper function
    def dbt_nodename_format(node_name):
        return node_name.split(".")[-1]

    # Read input JSON file from S3
    response = s3.get_object(Bucket=input_bucket, Key=input_key)
    file_content = response['Body'].read().decode('utf-8')
    data = json.loads(file_content)
    lineage_map = data["child_map"]
    node_dict = {}
    dbt_lineage_map = {}

    # Process data
    for item in lineage_map:
        lineage_map[item] = [dbt_nodename_format(child) for child in lineage_map[item]]
        node_dict[item] = dbt_nodename_format(item)

    # Update key names
    lineage_map = {node_dict[old]: value for old, value in lineage_map.items()}
    dbt_lineage_map["lineage_map"] = lineage_map

    # Convert result to JSON string
    result_json = json.dumps(dbt_lineage_map)

    # Write JSON string to S3
    s3.put_object(Body=result_json, Bucket=output_bucket, Key=output_key)
    print(f"Data written to s3://{output_bucket}/{output_key}")

    return {
        'statusCode': 200,
        'body': json.dumps('Athena data lineage processing completed successfully')
    }

Merge preprocessed lineage data and write to Neptune using Lambda functions

  1. Before processing data with the Lambda function, create a Lambda layer by uploading the required Gremlin plugin. For detailed steps on creating and configuring Lambda Layers, see the AWS Lambda Layers documentation.

Because connecting Lambda to Neptune for constructing a DAG requires the Gremlin plugin, it needs to be uploaded before using Lambda. The Gremlin package can be obtained from the Data Lineage Graph Construction GitHub repository.

Figure 9-Lambda layers

  1. Create a new Lambda function. Choose the function to configure. To the recently created layer, at the bottom of the page, choose Add a layer.

Figure 10_Add a layer

Create another Lambda layer for the requests library, similar to how you created the layer for the Gremlin plugin. This library will be used for HTTP client functionality in the Lambda function.

  1. Choose the recently created Lambda function to configure. Connect to Neptune through Lambda to merge the two datasets and construct a DAG. On the Code tab, the reference code to execute is as follows:
import json
import boto3
import os
import requests
from botocore.auth import SigV4Auth
from botocore.awsrequest import AWSRequest
from botocore.credentials import get_credentials
from botocore.session import Session
from concurrent.futures import ThreadPoolExecutor, as_completed

def read_s3_file(s3_client, bucket, key):
    try:
        response = s3_client.get_object(Bucket=bucket, Key=key)
        data = json.loads(response['Body'].read().decode('utf-8'))
        return data.get("lineage_map", {})
    except Exception as e:
        print(f"Error reading S3 file {bucket}/{key}: {str(e)}")
        raise

def merge_data(athena_data, redshift_data):
    return {**athena_data, **redshift_data}

def sign_request(request):
    credentials = get_credentials(Session())
    auth = SigV4Auth(credentials, 'neptune-db', os.environ['AWS_REGION'])
    auth.add_auth(request)
    return dict(request.headers)

def send_request(url, headers, data):
    try:
        response = requests.post(url, headers=headers, data=data, timeout=30)
        response.raise_for_status()
        return response.text
    except requests.exceptions.RequestException as e:
        print(f"Request Error: {str(e)}")
        if hasattr(e.response, 'text'):
            print(f"Response content: {e.response.text}")
        raise

def write_to_neptune(data):
    endpoint = 'https://your neptune endpoint name:8182/gremlin'
    # replace with your neptune endpoint name

    # Clear Neptune database
    clear_query = "g.V().drop()"
    request = AWSRequest(method='POST', url=endpoint, data=json.dumps({'gremlin': clear_query}))
    signed_headers = sign_request(request)
    response = send_request(endpoint, signed_headers, json.dumps({'gremlin': clear_query}))
    print(f"Clear database response: {response}")

    # Verify if the database is empty
    verify_query = "g.V().count()"
    request = AWSRequest(method='POST', url=endpoint, data=json.dumps({'gremlin': verify_query}))
    signed_headers = sign_request(request)
    response = send_request(endpoint, signed_headers, json.dumps({'gremlin': verify_query}))
    print(f"Vertex count after clearing: {response}")
    
    def process_node(node, children):
        # Add node
        query = f"g.V().has('lineage_node', 'node_name', '{node}').fold().coalesce(unfold(), addV('lineage_node').property('node_name', '{node}'))"
        request = AWSRequest(method='POST', url=endpoint, data=json.dumps({'gremlin': query}))
        signed_headers = sign_request(request)
        response = send_request(endpoint, signed_headers, json.dumps({'gremlin': query}))
        print(f"Add node response for {node}: {response}")

        for child_node in children:
            # Add child node
            query = f"g.V().has('lineage_node', 'node_name', '{child_node}').fold().coalesce(unfold(), addV('lineage_node').property('node_name', '{child_node}'))"
            request = AWSRequest(method='POST', url=endpoint, data=json.dumps({'gremlin': query}))
            signed_headers = sign_request(request)
            response = send_request(endpoint, signed_headers, json.dumps({'gremlin': query}))
            print(f"Add child node response for {child_node}: {response}")

            # Add edge
            query = f"g.V().has('lineage_node', 'node_name', '{node}').as('a').V().has('lineage_node', 'node_name', '{child_node}').coalesce(inE('lineage_edge').where(outV().as('a')), addE('lineage_edge').from('a').property('edge_name', ' '))"
            request = AWSRequest(method='POST', url=endpoint, data=json.dumps({'gremlin': query}))
            signed_headers = sign_request(request)
            response = send_request(endpoint, signed_headers, json.dumps({'gremlin': query}))
            print(f"Add edge response for {node} -> {child_node}: {response}")

    with ThreadPoolExecutor(max_workers=10) as executor:
        futures = [executor.submit(process_node, node, children) for node, children in data.items()]
        for future in as_completed(futures):
            try:
                future.result()
            except Exception as e:
                print(f"Error in processing node: {str(e)}")

def lambda_handler(event, context):
    # Initialize S3 client
    s3_client = boto3.client('s3')

    # S3 bucket and file paths
    bucket_name = 'data-lineage-analysis' # Replace with your S3 bucket name
    athena_key = 'athena_dbt_lineage_map.json' # Replace with your athena lineage key value output json name
    redshift_key = 'redshift_dbt_lineage_map.json' # Replace with your redshift lineage key value output json name

    try:
        # Read Athena lineage data
        athena_data = read_s3_file(s3_client, bucket_name, athena_key)
        print(f"Athena data size: {len(athena_data)}")

        # Read Redshift lineage data
        redshift_data = read_s3_file(s3_client, bucket_name, redshift_key)
        print(f"Redshift data size: {len(redshift_data)}")

        # Merge data
        combined_data = merge_data(athena_data, redshift_data)
        print(f"Combined data size: {len(combined_data)}")

        # Write to Neptune (including clearing the database)
        write_to_neptune(combined_data)

        return {
            'statusCode': 200,
            'body': json.dumps('Data successfully written to Neptune')
        }
    except Exception as e:
        print(f"Error in lambda_handler: {str(e)}")
        return {
            'statusCode': 500,
            'body': json.dumps(f'Error: {str(e)}')
        }

Create Step Functions workflow

  1. On the Step Functions console, choose State machines, and then choose Create state machine. On the Choose a template page, select Blank template.

Figure 11-Step Functions blank template

  1. In the Blank template, choose Code to define your state machine. Use the following example code:
{
  "Comment": "Daily Data Lineage Processing Workflow",
  "StartAt": "Parallel Processing",
  "States": {
    "Parallel Processing": {
      "Type": "Parallel",
      "Branches": [
        {
          "StartAt": "Process Athena Data",
          "States": {
            "Process Athena Data": {
              "Type": "Task",
              "Resource": "arn:aws:states:::lambda:invoke",
              "Parameters": {
                "FunctionName": "athena-data-lineange-process-Lambda", ##Replace with your Athena data lineage process Lambda function name
                "Payload": {
                  "input.$": "$"
                }
              },
              "End": true
            }
          }
        },
        {
          "StartAt": "Process Redshift Data",
          "States": {
            "Process Redshift Data": {
              "Type": "Task",
              "Resource": "arn:aws:states:::lambda:invoke",
              "Parameters": {
                "FunctionName": "redshift-data-lineange-process-Lambda", ##Replace with your Redshift data lineage process Lambda function name
                "Payload": {
                  "input.$": "$"
                }
              },
              "End": true
            }
          }
        }
      ],
      "Next": "Load Data to Neptune"
    },
    "Load Data to Neptune": {
      "Type": "Task",
      "Resource": "arn:aws:states:::lambda:invoke",
      "Parameters": {
        "FunctionName": "data-lineage-analysis-lambda" ##Replace with your Lambda function Name
      },
      "End": true
    }
  }
}
  1. After completing the configuration, choose the Design tab to view the workflow shown in the following diagram.

Figure 12-Step Functions design view

Create scheduling rules with Amazon EventBridge

Configure Amazon EventBridge to generate lineage data daily during off-peak business hours. To do this:

  1. Create a new rule in the EventBridge console with a descriptive name.
  2. Set the rule type to “Schedule” and configure it to run once daily (using either a fixed rate or the Cron expression “0 0 * * ? *”).
  3. Select the AWS Step Functions state machine as the target and specify the state machine you created earlier.

Query results in Neptune

  1. On the Neptune console, select Notebooks. Open an existing notebook or create a new one.

Figure 13-Neptune notebook

  1. In the notebook, create a new code cell to perform a query. The following code example shows the query statement and its results:
%%gremlin -d node_name -de edge_name
g.V().hasLabel('lineage_node').outE('lineage_edge').inV().hasLabel('lineage_node').path().by(elementMap())

You can now see the end-to-end data lineage graph information for both dbt on Athena and dbt on Amazon Redshift. The following image shows the merged DAG data lineage graph in Neptune.

Figure 14-Merged DAG data lineage graph in Neptune

You can query the generated data lineage graph for data related to a specific table, such as title_crew.

The sample query statement and its results are shown in the following code example:

%%gremlin -d node_name -de edge_name
g.V().has('lineage_node', 'node_name', 'title_crew')
  .repeat(
    union(
      __.inE('lineage_edge').outV(),
      __.outE('lineage_edge').inV()
    )
  )
  .until(
    __.has('node_name', within('names', 'genre_titles', 'titles'))
    .or()
    .loops().is(gt(10))
  )
  .path()
  .by(elementMap())

The following image shows the filtered results based on title_crew table in Neptune.

Figure 15-Filtered results based on title_crew table in Neptune

Clean up

To clean up your resources, complete the following steps:

  1. Delete EventBridge rules
# Stop new events from triggering while removing dependencies
aws events disable-rule --name <rule-name>
# Break connections between rule and targets (like Lambda functions)
aws events remove-targets --rule <rule-name> --ids <target-id>
# Remove the rule completely from EventBridge
aws events delete-rule --name <rule-name>
  1. Delete Step Functions state machine
# Stop all running executions
aws stepfunctions stop-execution --execution-arn <execution-arn>
# Delete the state machine
aws stepfunctions delete-state-machine --state-machine-arn <state-machine-arn>
  1. Delete Lambda functions
# Delete Lambda function
aws lambda delete-function --function-name <function-name>
# Delete Lambda layers (if used)
aws lambda delete-layer-version --layer-name <layer-name> --version-number <version>
  1. Clean up the Neptune database
# Delete all snapshots
aws neptune delete-db-cluster-snapshot --db-cluster-snapshot-identifier <snapshot-id>
# Delete database instance
aws neptune delete-db-instance --db-instance-identifier <instance-id> --skip-final-snapshot
# Delete database cluster
aws neptune delete-db-cluster --db-cluster-identifier <cluster-id> --skip-final-snapshot
  1. Follow the instructions at Deleting a single object to clean up the S3 buckets

Conclusion

In this post, we demonstrated how dbt enables unified data modeling across Amazon Athena and Amazon Redshift, integrating data lineage from both one-time and complex queries. By using Amazon Neptune, this solution provides comprehensive end-to-end lineage analysis. The architecture uses AWS serverless computing and managed services, including Step Functions, Lambda, and EventBridge, providing a highly flexible and scalable design.

This approach significantly lowers the learning curve through a unified data modeling method while enhancing development efficiency. The end-to-end data lineage graph visualization and analysis not only strengthen data governance capabilities but also offer deep insights for decision-making.

The solution’s flexible and scalable architecture effectively optimizes operational costs and improves business responsiveness. This comprehensive approach balances technical innovation, data governance, operational efficiency, and cost-effectiveness, thus supporting long-term business growth with the adaptability to meet evolving enterprise needs.

With OpenLineage-compatible data lineage now generally available in Amazon DataZone, we plan to explore integration possibilities to further enhance the system’s capability to handle complex data lineage analysis scenarios.

If you have any questions, please feel free to leave a comment in the comments section.


About the authors

nancynwu+photo

Nancy Wu is a Solutions Architect at AWS, responsible for cloud computing architecture consulting and design for multinational enterprise customers. Has many years of experience in big data, enterprise digital transformation research and development, consulting, and project management across telecommunications, entertainment, and financial industries.

Xu+Feng+PhotoXu Feng is a Senior Industry Solution Architect at AWS, responsible for designing, building, and promoting industry solutions for the Media & Entertainment and Advertising sectors, such as intelligent customer service and business intelligence. With 20 years of software industry experience, currently focused on researching and implementing generative AI and AI-powered data solutions.

Xu+Da+PhotoXu Da is a Amazon Web Services (AWS) Partner Solutions Architect based out of Shanghai, China. He has more than 25 years of experience in IT industry, software development and solution architecture. He is passionate about collaborative learning, knowledge sharing, and guiding community in their cloud technologies journey.

Read and write S3 Iceberg table using AWS Glue Iceberg Rest Catalog from Open Source Apache Spark

Post Syndicated from Raj Ramasubbu original https://aws.amazon.com/blogs/big-data/read-and-write-s3-iceberg-table-using-aws-glue-iceberg-rest-catalog-from-open-source-apache-spark/

In today’s data-driven world, organizations are constantly seeking efficient ways to process and analyze vast amounts of information across data lakes and warehouses.

Enter Amazon SageMaker Lakehouse, which you can use to unify all your data across Amazon Simple Storage Service (Amazon S3) data lakes and Amazon Redshift data warehouses, helping you build powerful analytics and AI and machine learning (AI/ML) applications on a single copy of data. SageMaker Lakehouse gives you the flexibility to access and query your data in-place with all Apache Iceberg compatible tools and engines. This opens up exciting possibilities for Open Source Apache Spark users who want to use SageMaker Lakehouse capabilities. Further you can secure your data in SageMaker Lakehouse by defining fine-grained permissions, which are enforced across all analytics and ML tools and engines.

In this post, we will explore how to harness the power of Open source Apache Spark and configure a third-party engine to work with AWS Glue Iceberg REST Catalog. The post will include details on how to perform read/write data operations against Amazon S3 tables with AWS Lake Formation managing metadata and underlying data access using temporary credential vending.

Solution overview

In this post, the customer uses Data Catalog to centrally manage technical metadata for structured and semi-structured datasets in their organization and wants to enable their data team to use Apache Spark for data processing. The customer will create an AWS Glue database and configure Apache Spark to interact with Glue Data Catalog using the Iceberg Rest API for writing/reading Iceberg data on Amazon S3 using Lake Formation permission control.

We will start by running an extract, transform, and load (ETL) script using Apache Spark to create an Iceberg table on Amazon S3 and access the table using the Glue Iceberg REST Catalog. The ETL script will add data to the Iceberg table and then read it back using Spark SQL. This post will showcase how this data can also be queried by other data teams using Amazon Athena .

Prerequisites

Access to an AWS Identity and Access Management (IAM) role that is a Lake Formation data lake administrator in the account that has the Data Catalog. For instructions, see Create a data lake administrator.

  1. Verify that you have Python version 3.7 or later installed. Check if pip3 version is 22.2.2 or higher is installed.
  2. Install or update the latest AWS Command Line Interface (AWS CLI). For instructions, see Installing or updating the latest version of the AWS CLI. Run aws configure using AWS CLI to point to your AWS account.
  3. Create an S3 bucket to store the customer Iceberg table. For this post, we will be using the us-east-2 AWS Region and will name the bucket: ossblog-customer-datalake.
  4. Create an IAM role that will be used in OSS Spark for data access using an AWS Glue Iceberg REST catalog endpoint. Make sure that the role has AWS Glue and Lake Formation policies as defined in Data engineer permissions. For this post, we will use an IAM role named spark_role.

Enable Lake Formation permissions for third-party access

In this section, you will register the S3 bucket with Lake Formation. This step allows Lake Formation to act as a centralized permissions management system for metadata and data stored in Amazon S3, enabling more efficient and secure data governance in data lake environments.

  1. Create a user defined IAM role following the instructions in Requirements for roles used to register locations. For this post, we will use the IAM role: LFRegisterRole.
  2. Register the S3 bucket ossblog-customer-datalake using the IAM role LFRegisterRole by running the following command:
    aws lakeformation register-resource \
    --resource-arn '< S3 bucket ARN for amzn-s3-demo-bucket>' \
    --role-arn '< IAM Role ARN for LFRegisterRole >' \
    --region <aws_region>

Alternatively you can use the AWS Management Console for Lake Formation.

  1. Navigate to the Lake Formation console, choose Administration in the navigation pane, and then Data lake locations and provide the following values:
    1. For Amazon S3 path, select s3://ossblog-customer-datalake.
    2. For IAM role, select LFRegisterRole
    3. For Permission mode, choose Lake Formation.
    4. Choose Register location.
  1. In Lake Formation, enable full table access for external engines to access data.
    1. Sign in as an admin user, choose Administration in the navigation pane.
    2. Choose Application integration settings and select Allow external engines to access data in Amazon S3 locations with full table access.
    3. Choose Save.

Set up resource access for the OSS Spark role:

  1. Create an AWS Glue database called ossblogdb in the default catalog by going to the Lake Formation console and choosing Databases in the navigation pane.
  2. Select the database, choose Edit and clear the checkbox for Use only IAM access control for new tables in this database.

Grant resource permission to OSS  Spark role:

To enable OSS Spark to create and populate the dataset in the ossblogdb database, you will use the IAM role (spark_role) for Apache Spark instance that you created in step 4 of the prerequisites section. Apache Spark will assume this role to create an Iceberg table, add records to it and read from it. To enable this functionality, grant full table access to spark_role and provide data location permission to the S3 bucket where the table data can be stored.

Grant create table permission to the spark_role:

Sign in as Datalake Admin and run the following command using AWS CLI:

aws lakeformation grant-permissions \
--principal '{"DataLakePrincipalIdentifier":"arn:aws:iam::<aws_account_id>:role/<iam_role_name>"}' \
--permissions '["CREATE_TABLE","DESCRIBE"]'\
--resource '{"Database":{"CatalogId":"<aws_account_id>","Name":"ossblogdb"}}' \
--region <aws_region>

Alternatively on the console:

  1. In the Lake Formation console navigation pane, choose Data lake permissions, and then choose Grant.
  2. In the Principals section, for IAM users and roles, select spark_role.
  3. In the LF-Tags or catalog resources section, select Named Data Catalog resources:
    1. Select <accountid> for Catalogs.
    2. Select ossblogdb for Databases.
  4. Select DESCRIBE and CREATE TABLE for Database permissions.
  5. Choose Grant.

Grant data location permission to the spark_role:

Sign in as Datalake Admin and run the following command using the AWS CLI:

aws lakeformation grant-permissions 
--principal '{"DataLakePrincipalIdentifier":"<Principal>"}' 
--permissions DATA_LOCATION_ACCESS 
--resource '{"DataLocation":{"CatalogId":"<Catalog ID>","ResourceArn":"<S3 bucket ARN>"}}' 
--region <aws_region>

Alternatively on the console:

  1. In the Lake Formation console navigation pane, choose Data Locations, and then choose Grant.
  2. For IAM users and roles, select spark_role.
  3. For Storage locations, select the bucket_name
  4. Choose Grant.

Set up a Spark script to use an AWS Glue Iceberg REST catalog endpoint:

Create a file named oss_spark_customer_etl.py in your environment with the following content:

import sys
import os
import time
from pyspark.sql import SparkSession

#Replace <aws_region> with AWS region name.
#Replace <aws_account_id> with AWS account ID.

spark = SparkSession.builder.appName('osspark') \
.config('spark.jars.packages', 'org.apache.iceberg:iceberg-spark-runtime-3.5_2.12:1.4.1,software.amazon.awssdk:bundle:2.20.160,software.amazon.awssdk:url-connection-client:2.20.160') \
.config('spark.sql.extensions', 'org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions') \
.config('spark.sql.defaultCatalog', 'spark_catalog') \
.config('spark.sql.catalog.spark_catalog', 'org.apache.iceberg.spark.SparkCatalog') \
.config('spark.sql.catalog.spark_catalog.type', 'rest') \
.config('spark.sql.catalog.spark_catalog.uri','https://glue.<aws_region>.amazonaws.com/iceberg') \
.config('spark.sql.catalog.spark_catalog.warehouse','<aws_account_id>') \
.config('spark.sql.catalog.spark_catalog.rest.sigv4-enabled','true') \
.config('spark.sql.catalog.spark_catalog.rest.signing-name','glue') \
.config('spark.sql.catalog.spark_catalog.rest.signing-region', <aws_region>) \
.config('spark.sql.catalog.spark_catalog.io-impl','org.apache.iceberg.aws.s3.S3FileIO') \
.config('spark.hadoop.fs.s3a.aws.credentials.provider','org.apache.hadoop.fs.s3a.SimpleAWSCredentialProvider') \
.config('spark.sql.catalog.spark_catalog.rest-metrics-reporting-enabled','false') \
.getOrCreate()
spark.sql("use ossblogdb").show()
spark.sql("""CREATE TABLE ossblogdb.customer (name string) USING iceberg location 's3://<3_bucket_name>/customer'""")
time.sleep(120)
spark.sql("insert into ossblogdb.customer values('Alice') ").show()
spark.sql("select * from ossblogdb.customer").show()

Launch Pyspark locally and validate read/write to the Iceberg table on Amazon S3

Run pip install pyspark. Save the script locally and set the environment variables (AWS_ACCESS_KEY_ID, AWS_SECRET_ACCESS_KEY, and AWS_SESSION_TOKEN) with temporary credentials for the spark_role IAM role.

Run python /path/to/oss_spark_customer_etl.py

You can also use Athena to view the data in the Iceberg table:

To enable the other data team to view the content, provide read access to the data team IAM role using the Lake Formation console:

  1. In the Lake Formation console navigation pane, choose Data lake permissions, and then choose Grant.
  2. In the Principals section, for IAM users and roles choose <iam_role>.
  3. In the LF-Tags or catalog resources section, select Named Data Catalog resources:
    1. Select <accountid> for Catalogs.
    2. Select ossblogdb for Databases.
    3. Select customer for Tables.
  4. Select DESCRIBE and SELECT for Table permissions.
  5. Choose Grant.

Sign in as the IAM role and run the command:

SELECT * FROM "ossblogdb"."customer" limit 10;

Clean up

To clean up your resources, complete the following steps:

  1. Delete the resources database/table created in Data Catalog.
  2. Empty and then delete the S3 bucket

Conclusion

In this post, we’ve walked through the seamless integration between Apache Spark and an AWS Glue Iceberg Rest Catalog for accessing Iceberg tables in Amazon S3, demonstrating how to effectively perform read and write operations using Iceberg REST API. The beauty of this solution lies in its flexibility—whether you’re running Spark on bare metal servers in your data center, in a Kubernetes cluster, or any other environment, this architecture can be adapted to suit your needs.


About the Authors

Raj RamasubbuRaj Ramasubbu is a Sr. Analytics Specialist Solutions Architect focused on big data and analytics and AI/ML with Amazon Web Services. He helps customers architect and build highly scalable, performant, and secure cloud-based solutions on AWS. Raj provided technical expertise and leadership in building data engineering, big data analytics, business intelligence, and data science solutions for over 20 years prior to joining AWS. He helped customers in various industry verticals like healthcare, medical devices, life science, retail, asset management, car insurance, residential REIT, agriculture, title insurance, supply chain, document management, and real estate.

Srividya Parthasarathy is a Senior Big Data Architect on the AWS Lake Formation team. She works with product team and customer to build robust features and solutions for their analytical data platform.  She enjoys building data mesh solutions and sharing them with the community.

Pratik Das is a Senior Product Manager with AWS Lake Formation. He is passionate about all things data and works with customers to understand their requirements and build delightful experiences. He has a background in building data-driven solutions and machine learning systems in production.

How ANZ Institutional Division built a federated data platform to enable their domain teams to build data products to support business outcomes

Post Syndicated from Leo Ramsamy original https://aws.amazon.com/blogs/big-data/how-anz-institutional-division-built-a-federated-data-platform-to-enable-their-domain-teams-to-build-data-products-to-support-business-outcomes/

In today’s rapidly evolving financial landscape, data is the bedrock of innovation, enhancing customer and employee experiences and securing a competitive edge. Recognizing this paradigm shift, ANZ Institutional Division has embarked on a transformative journey to redefine its approach to data management, utilization, and extracting significant business value from data insights.

Like many large financial institutions, ANZ Institutional Division operated with siloed data practices and centralized data management teams. As time went on, the limitations of this approach became apparent due to rising data complexity, larger volumes, and the growing demand for swift, business-driven insights. Consequently, the bank encountered several challenges and needed to take the following actions:

  • Create business insights from untapped data potential, estimated to be approximately $150 million in the Institutional Division alone
  • Improve operational efficiency by removing manual data handling, the use of spreadsheets, and duplicate data entries
  • Increase agility by making data expertise more readily available, thereby improving time to market and overall customer experience
  • Address data quality
  • Standardize tooling and remove the Shadow IT culture, driving scalability, reducing risk, and minimizing overall operational inefficiencies

These challenges are not unique to ANZ Institutional Division. Globally, financial institutions have been experiencing similar issues, prompting a widespread reassessment of traditional data management approaches.

One major trend, embraced by many financial institutions, has been the adoption of the data mesh architecture and the shift towards treating data as a product. This paradigm, pioneered by thought leaders like Zhamak Dehghani, introduces a decentralized approach to data management that aligns closely with modern organizational structures and agile methodologies.

Some notable global examples of leading companies embracing and implementing this trend are JPMorgan Chase, Capital One, and Saxo Bank.

Inspired by these global trends and driven by its own unique challenges, ANZ’s Institutional Division decided to pivot from viewing data as a byproduct of projects to treating it as a valuable product in its own right.

This shift promises several business benefits:

  • Empowered domain expertise – By decentralizing data ownership to domain-based teams, ANZ can use the deep business knowledge within each unit to create more relevant and valuable data products
  • Increased agility – Domain teams can now respond more quickly to business needs, creating and iterating on data products without relying on a centralized bottleneck
  • Improved data quality – With domain experts overseeing their own data, there’s a greater likelihood of catching and correcting quality issues at the source
  • Scalability – The federated approach allows for greater scalability, enabling ANZ to handle increasing data volumes and complexity more effectively
  • Innovation catalyst – By democratizing data access and empowering teams to create data products, ANZ is fostering a culture of innovation and data-driven decision-making across the organization

This transition is not just about technology; it represents a fundamental shift in how ANZ views and values its data assets. By treating data as a product, the bank is positioned to not only overcome current challenges, but to unlock new opportunities for growth, customer service, and competitive advantage.

This post explores how the shift to a data product mindset is being implemented, the challenges faced, and the early wins that are shaping the future of data management in the Institutional Division.

ANZ’s federated data strategy

In response to the challenges, ANZ Group formulated a data strategy that focuses on empowering employees to securely use data to improve the sustainability and financial well-being of their customers. At its core are the following pillars:

  • Introducing new ways of working that focus on generating customer value first
  • New technology platforms and tooling that allow the bank to collect, share, archive, and dispose data in a secure and controlled way
  • Achieving consistency in how data is produced and consumed across the entire bank through data products and better-connected systems
  • Supporting the bank’s risk and regulatory obligations by providing a secure and resilient data platform that provides fine-grained, controlled access to quality data products

ANZ has made the strategic decision to adopt an architectural and operational model aligned with the data mesh paradigm, which revolves around four key principles: domain ownership, data as a product, a self-serve data platform, and federated computational governance.

Domain ownership recognizes that the teams generating the data have the deepest understanding of it and are therefore best suited to manage, govern, and share it effectively. This principle makes sure data accountability remains close to the source, fostering higher data quality and relevance.

Treating data as a product instils a product-centric mindset, emphasizing that data must be secure, discoverable, understandable, interoperable, reusable, and managed throughout its lifecycle. This principle makes sure data consumers, both internal and external, derive consistent value from well-designed data products.

A self-serve data platform empowers domains to create, discover, and consume data products independently. It abstracts technical complexities and provides user-friendly tools, enabling a scalable, repeatable, and automated approach to producing high-quality data products.

Under the federated mesh architecture, each divisional mesh functions as a node within the broader enterprise data mesh, maintaining a degree of autonomy in managing its data products. To effectively coordinate these autonomous nodes and facilitate seamless integration, enterprise-wide standards, such as those related to data governance, interoperability, and security, are essential to maintain alignment and consistency across all nodes and domains and teams within.

With this approach, each node in ANZ maintains its divisional alignment and adherence to data risk and governance standards and policies to manage local data products and data assets. This enables global discoverability and collaboration without centralizing ownership or operations.

As a result, governance resides with the data products themselves, making sure standards and policies, such as access control, data quality, and compliance, are enforced where the data lives. In this regard, the enterprise data product catalog acts as a federated portal, facilitating cross-domain access and interoperability while maintaining alignment with governance principles. This model balances node or domain-level autonomy with enterprise-level oversight, creating a scalable and consistent framework across ANZ.

Within the ANZ enterprise data mesh strategy, aligning data mesh nodes with the ANZ Group’s divisional structure provides optimal alignment between data mesh principles and organizational structure, as shown in the following diagram.

Central to the success of this strategy is its support for each division’s autonomy and freedom to choose their own domain structure, which is closely aligned to their business needs. Divisions decide how many domains to have within their node; some may have one, others many. These nodes can implement analytical platforms like data lake houses, data warehouses, or data marts, all united by producing data products. Nodes and domains serve business needs and are not technology mandated.

Under the federated computational governance model, the ANZ Group strategy defines guardrails that treat a node as a logical data container suitable for the following:

  • Ingestion and metadata management
  • Creating source-aligned data products complying with ANZ’s Data Product Specification (DPS)
  • Integrating source-aligned data products from other nodes
  • Producing consumer-aligned data products for specific business purposes
  • Publishing conforming data products to ANZ’s Data Product Catalog (DPC)

Following on from this strategy is organizing its domain structure to provide autonomy to various functional teams while preserving the core values of data mesh. The following diagram depicts an example of the possible structure.

For instance, Domain A will have the flexibility to create data products that can be published to the divisional catalog, while also maintaining the autonomy to develop data products that are exclusively accessible to teams within the domain. These products will not be available to others until they are deemed ready for broader enterprise use.

This strategy supports each division’s autonomy to implement their own data catalogs and decide which data products to publish to the group-level catalog. This flexibility extends to divisional domains, which can choose which data products to publish to the divisional catalog or keep visible only to domain consumers.

Institutional Data & AI Platform architecture

The Institutional Division has implemented a self-service data platform to enable the domain teams to build and manage data products autonomously. The Institutional Data & AI platform adopts a federated approach to data while centralizing the metadata to facilitate simpler discovery and sharing of data products. The following diagram illustrates the building blocks of the Institutional Data & AI Platform.

The building blocks are as follows:

  1. Foundational Data & AI Platform capabilities – A dedicated data platform team provides domain-agnostic tools, systems, and capabilities to enable autonomous data product development across domains. This self-serve infrastructure allows domain teams to manage the full data lifecycle without relying on a centralized data team. Key capabilities include data storage, data onboarding and transformation, and data utilities that facilitate data sharing with interoperability between domains. These capabilities abstract the technical complexities associated with data management infrastructure, allowing domain experts to focus on creating valuable data products rather than infrastructure management.
  2. Domain-owned data assets – The domain-oriented data ownership approach distributes responsibility for data across the business units within the Institutional Division. Domain teams are responsible for developing, deploying, and managing their own analytical data products alongside operational data services. Data contracts authored by data product owners automate data product creation and provide a standard to access data products. By treating the data as a product, the outcome is a reusable asset that outlives a project and meets the needs of the enterprise consumer. Consumer feedback and demand drives creation and maintenance of the data product.
  3. Division-level metadata management and data governance – A centrally hosted service provides domain teams with the capability to publish their data products along with relevant metadata, like business definitions and lineage. Some of the key features implemented are:
    1. Metadata management that centralizes metadata and presents it within the context of data products, such as data quality scores and data product lineage.
    2. A data portal for consumers to discover data products and access associated metadata.
    3. Subscription workflows that simplify access management to the data products.
    4. Computational governance that enforces divisional and enterprise data policies and standards, such as data classification and business data models for aligning terminology.

The following diagram is a high-level example of the technical architecture approach towards the Institutional Data & AI Platform. The solution uses a building block approach, on a cloud-centered platform comprised of AWS services, with partner solutions and open standards like OpenLineage and Apache Iceberg.

Let’s look at the key services that enable the federated platform to operate at scale:

  • Data storage and processing:
    • Apache Iceberg on Amazon Simple Storage Service (Amazon S3) offers an optimized way to store data assets and products and promotes interoperability across other services
    • Amazon Redshift allows domain teams to create and manage fit-for-purpose data marts
    • AWS Lambda and AWS Glue are used for data onboarding and processing, and data utilities created in Python and PySpark promote reusability and quality across the data processing pipelines
    • dbt simplifies data transformation rules and allows sub-domain data analysts to build modeling logic as SQL statements
    • Amazon Managed Workflows for Apache Airflow (Amazon MWAA) enables efficient management of workflows and data pipeline orchestration using out-of-the-box integrations with AWS services
  • Metadata management and data governance:
    • To maintain data reliability and accuracy, a robust data quality framework using Soda core is used that automates data quality using checks defined in a data contract
    • Amazon DataZone enables data product cataloging, discovery, metadata management, and implementing computational governance
    • OpenLineage simplifies harvesting and collection of data and process-level lineage, which are then published to Amazon DataZone
    • AWS Lake Formation, combined with AWS Glue Data Catalog, provides data governance and access management to data products that reside within sub-domains
  • Analytics:
    • Tableau offers capabilities for sub-domains with data visualization and business intelligence capabilities
  • Observability and security:
    • Observability needs of the platform are built into all the processes using monitoring, with logging functionality provided by Amazon CloudWatch and AWS CloudTrail
    • AWS Secrets Manager makes sure secrets are stored and made available for data pipelines to access services in a secure manner

The technical implementation actualizes the data product strategy at ANZ Institutional Division. Amazon DataZone plays an essential role in facilitating data product management for the domain teams. The service addresses several critical aspects of the Institutional Division’s data product strategy, including:

  • Data cataloging and metadata management – Amazon DataZone provides comprehensive data cataloging and metadata management capabilities
  • Data governance and compliance – Effective data governance is essential for scaling data products
  • Self-service capabilities – Amazon DataZone empowers domain teams with self-service capabilities, enabling them to create, manage, and deploy data products independently
  • Integration and interoperability – One of the challenges in scaling data products is providing seamless integration across various data sources and systems
  • Collaboration and sharing – Amazon DataZone provides a platform for sharing data and metadata across teams and domains

Institutional Division’s delivery model to achieve scale

The Institutional Division has successfully used the federated architecture, and key to this delivery model is the implementation of Foundational Data & AI Platform capabilities that serve all domains within the division. This model promotes self-service and accelerates the delivery of subsequent initiatives by using the capabilities built for previous use cases.

To evaluate the success of the delivery model, ANZ has implemented key metrics, such as cost transparency and domain adoption, to guide the data mesh governance team in refining the delivery approach. For instance, one enhancement involves integrating cross-functional squads to support data literacy.

The key to scaling the Institutional Division operating model are the following considerations:

  • Data as a product approach – Use techniques like event storming and domain-driven design to capture business events and their meanings.
  • Education and enablement – Conduct learning interventions to upskill teams on understanding and using the data as a product approach.
  • Iterative data platform delivery – Work backward from business initiative to iteratively deliver self-service data platform infrastructure capabilities.
  • Managing demand efficiently – Implement a feedback mechanism to manage demand on data products. Track and manage data debt using standard data contract specifications. Most importantly, adopt governance and standards to make sure data products are built and maintained with a long-term perspective, minimizing technical debt.

“The Institutional Data & Analytics Platform (IDAP) has allowed the Institutional team to establish a base foundation to allow various teams to aggregate and consume the wealth of data across the division. This self-service platform enables business leaders to both create and consume reusable data products, unlocking value across this division. It’s also an excellent proof point for our broader data mesh architecture, allowing us to connect this divisional data to broader enterprise data stores—further positioning us to put the customer at the center of everything we do.”

– Tim Hogarth, CTO ANZ

“AWS believes that democratizing data, while not compromising on security and fine-grained access, is a key component of any future-proof, scalable data platform, so we are pleased to be enabling ANZ bank’s IDAP metadata management and data governance capabilities through Amazon DataZone. This allows the diverse business functions at ANZ the autonomy to self-serve on their data needs with built-in governance.”

– Shikha Verma, Head of Product, Amazon DataZone

Conclusion

ANZ’s journey to move towards a data product approach has improved the organization’s approach to manage data and reduce data silos, and has positioned it to become a data-driven, customer-centric organization. By combining federated platform practices and adopting AWS services and open standards, ANZ Institutional Division is achieving its objectives in decentralization with a scalable data platform that enables its domain teams to make informed decisions, drive innovation, and maintain a competitive edge.

Special thanks: This implementation success is a result of close collaboration between ANZ Institutional Division, AWS ProServe, and the AWS account team. We want to thank ANZ Institutional Executives and the Leadership Team for the strong sponsorship and direction.


About the Authors

Leo Ramsamy is a Platform Architect specializing in data and analytics for ANZ’s Institutional division. He focuses on modern data practices, including Data Mesh architecture, data governance, quality management, and observability. His work aligns data strategies with business goals, improving accessibility and enabling better decision-making across ANZ.

Srinivasan Kuppusamy is a Senior Cloud Architect – Data at AWS ProServe, where he helps customers solve their business problems using the power of AWS Cloud technology. His areas of interests are data and analytics, data governance, and AI/ML.

Rada Stanic is a Chief Technologist at Amazon Web Services, where she helps ANZ customers across different segments solve their business problems using AWS Cloud technologies. Her special areas of interest are data analytics, machine learning/AI, and application modernization.

Amazon SageMaker Lakehouse and Amazon Redshift supports zero-ETL integrations from applications

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/introducing-amazon-sagemaker-lakehouse-support-for-zero-etl-integrations-from-applications/

Today, we announced the general availability of Amazon SageMaker Lakehouse and Amazon Redshift support for zero-ETL integrations from applications. Amazon SageMaker Lakehouse unifies all your data across Amazon Simple Storage Service (Amazon S3) data lakes and Amazon Redshift data warehouses, helping you build powerful analytics and AI/ML applications on a single copy of data. SageMaker Lakehouse gives you the flexibility to access and query your data in-place with all Apache Iceberg compatible tools and engines. Zero-ETL is a set of fully managed integrations by AWS that minimizes the need to build ETL data pipelines for common ingestion and replication use cases. With zero-ETL integrations from applications such as Salesforce, SAP, and Zendesk, you can reduce time spent building data pipelines and focus on running unified analytics on all your data in Amazon SageMaker Lakehouse and Amazon Redshift.

As organizations rely on an increasingly diverse array of digital systems, data fragmentation has become a significant challenge. Valuable information is often scattered across multiple repositories, including databases, applications, and other platforms. To harness the full potential of their data, businesses must enable access and consolidation from these varied sources. In response to this challenge, users build data pipelines to extract and load (EL) from multiple applications into centralized data lakes and data warehouses. Using zero-ETL, you can efficiently replicate valuable data from your customer support, relationship management, and enterprise resource planning (ERP) applications for analytics and AI/ML to datalakes and data warehouses, saving you weeks of engineering effort needed to design, build, and test data pipelines.

Prerequisites

  • An Amazon SageMaker Lakehouse catalog configured through AWS Glue Data Catalog and AWS Lake Formation.
  • An AWS Glue database that is configured for Amazon S3 where the data will be stored.
  • A secret in AWS Secret Manager to use for the connection to the data source. The credentials must contain the username and password that you use to sign in to your application.
  • An AWS Identity and Access Management (IAM) role for the Amazon SageMaker Lakehouse or Amazon Redshift job to use. The role must grant access to all resources used by the job, including Amazon S3 and AWS Secrets Manager.
  • A valid AWS Glue connection to the desired application.

How it works – creating a Glue connection prerequisite
I start by creating a connection using the AWS Glue console. I opt for a Salesforce integration as the data source.

Next, I provide the location of the Salesforce instance to be used for the connection, together with the rest of the required information. Be sure to use the .salesforce.com domain instead of .force.com. Users can choose between two authentication methods, JSON Web Token (JWT), which is obtained through Salesforce access tokens, or OAuth login through the browser.

I review all the information and then choose Create connection.

After I sign into the Salesforce instance through a popup (not shown here), the connection is successfully created.

How it works – creating a zero-ETL integration
Now that I have a connection, I choose zero-ETL integrations from the left navigation panel, then choose Create zero-ETL integration.

First I choose the source type for my integration – in this case Salesforce so I can use my recently created connection.

Next, I select objects from the data source that I want to replicate to the target database in AWS Glue.

While in the process of adding objects, I can quickly preview both data and metadata to confirm that I am selecting the correct object.

By default, zero-ETL integration will synchronize data from the source to the target every 60 minutes. However, you can change this interval to reduce the cost of replication for cases that do not require frequent updates.

I review and then choose Create and launch integration.

The data in the source (Salesforce instance) has now been replicated to the target database salesforcezeroETL in my AWS account. This integration has two phases. Phase 1: initial load will ingest all the data for the selected objects and may take between 15 min to a few hours depending on the size of the data in these objects. Phase 2: incremental load will detect any changes (such as new records, updated records, or deleted records) and apply these to the target.

Each of the objects that I selected earlier has been stored in its respective table within the database. From here I can view the Table data for each of the objects that have been replicated from the data source.

Lastly, here’s a view of the data in Salesforce. As new entities are created, or existing entities are updated or changed in Salesforce, the data changes will synchronize to the target in AWS Glue automatically.

Now available
Amazon SageMaker Lakehouse and Amazon Redshift support for zero-ETL integrations from applications is now available in US East (N. Virginia), US East (Ohio), US West (Oregon), Asia Pacific (Hong Kong), Asia Pacific (Singapore), Asia Pacific (Sydney), Asia Pacific (Tokyo), Europe (Frankfurt), Europe (Ireland), and Europe (Stockholm) AWS Regions. For pricing information, visit the AWS Glue pricing page.

To learn more, visit our AWS Glue User Guide. Send feedback to AWS re:Post for AWS Glue or through your usual AWS Support contacts. Get started by creating a new zero-ETL integration today.

– Veliswa

Simplify analytics and AI/ML with new Amazon SageMaker Lakehouse

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/simplify-analytics-and-aiml-with-new-amazon-sagemaker-lakehouse/

Today, I’m very excited to announce the general availability of Amazon SageMaker Lakehouse, a capability that unifies data across Amazon Simple Storage Service (Amazon S3) data lakes and Amazon Redshift data warehouses, helping you build powerful analytics and artificial intelligence and machine learning (AI/ML) applications on a single copy of data. SageMaker Lakehouse is a part of the next generation of Amazon SageMaker, which is a unified platform for data, analytics and AI, that brings together widely-adopted AWS machine learning and analytics capabilities and delivers an integrated experience for analytics and AI.

Customers want to do more with data. To move faster with their analytics journey, they are picking the right storage and databases to store their data. The data is spread across data lakes, data warehouses, and different applications, creating data silos that make it difficult to access and utilize. This fragmentation leads to duplicate data copies and complex data pipelines, which in turn increases costs for the organization. Furthermore, customers are constrained to use specific query engines and tools, as the way and where the data is stored limits their options. This restriction hinders their ability to work with the data as they would prefer. Lastly, the inconsistent data access makes it challenging for customers to make informed business decisions.

SageMaker Lakehouse addresses these challenges by helping you to unify data across Amazon S3 data lakes and Amazon Redshift data warehouses. It offers you the flexibility to access and query data in-place with all engines and tools compatible with Apache Iceberg. With SageMaker Lakehouse, you can define fine-grained permissions centrally and enforce them across multiple AWS services, simplifying data sharing and collaboration. Bringing data into your SageMaker Lakehouse is easy. In addition to seamlessly accessing data from your existing data lakes and data warehouses, you can use zero-ETL from operational databases such as Amazon Aurora, Amazon RDS for MySQL, Amazon DynamoDB, as well as applications such as Salesforce and SAP. SageMaker Lakehouse fits into your existing environments.

Get started with SageMaker Lakehouse
For this demonstration, I use a preconfigured environment that has multiple AWS data sources. I go to the Amazon SageMaker Unified Studio (preview) console, which provides an integrated development experience for all your data and AI. Using Unified Studio, you can seamlessly access and query data from various sources through SageMaker Lakehouse, while using familiar AWS tools for analytics and AI/ML.

This is where you can create and manage projects, which serve as shared workspaces. These projects allow team members to collaborate, work with data, and develop AI models together. Creating a project automatically sets up AWS Glue Data Catalog databases, establishes a catalog for Redshift Managed Storage (RMS) data, and provisions necessary permissions. You can get started by creating a new project or continue with an existing project.

To create a new project, I choose Create project.

I have 2 project profile options to build a lakehouse and interact with it. First one is Data analytics and AI-ML model development, where you can analyze data and build ML and generative AI models powered by Amazon EMR, AWS Glue, Amazon Athena, Amazon SageMaker AI, and SageMaker Lakehouse. Second one is SQL analytics, where you can analyze your data in SageMaker Lakehouse using SQL. For this demo, I proceed with SQL analytics.

I enter a project name in the Project name field and choose SQL analytics under Project profile. I choose Continue.

I enter the values for all the parameters under Tooling. I enter the values to create my Lakehouse databases. I enter the values to create my Redshift Serverless resources. Finally, I enter a name for my catalog under Lakehouse Catalog.

On the next step, I review the resources and choose Create project.

After the project is created, I observe the project details.

I go to Data in the navigation pane and choose the + (plus) sign to Add data. I choose Create catalog to create a new catalog and choose Add data.

After the RMS catalog is created, I choose Build from the navigation pane and then choose Query Editor under Data Analysis & Integration to create a schema under RMS catalog, create a table, and then load table with sample sales data.

After entering the SQL queries into the designated cells, I choose Select data source from the right dropdown menu to establish a database connection to Amazon Redshift data warehouse. This connection allows me to execute the queries and retrieve the desired data from the database.

Once the database connection is successfully established, I choose Run all to execute all queries and monitor the execution progress until all results are displayed.

For this demonstration, I use two additional pre-configured catalogs. A catalog is a container that organizes your lakehouse object definitions such as schema and tables. The first is an Amazon S3 data lake catalog (test-s3-catalog) that stores customer records, containing detailed transactional and demographic information. The second is a lakehouse catalog (churn_lakehouse) dedicated to storing and managing customer churn data. This integration creates a unified environment where I can analyze customer behavior alongside churn predictions.

From the navigation pane, I choose Data and locate my catalogs under the Lakehouse section. SageMaker Lakehouse offers multiple analysis options, including Query with Athena, Query with Redshift, and Open in Jupyter Lab notebook.

Note that you need to choose Data analytics and AI-ML model development profile when you create a project, if you want to use Open in Jupyter Lab notebook option. If you choose Open in Jupyter Lab notebook, you can interact with SageMaker Lakehouse using Apache Spark via EMR 7.5.0 or AWS Glue 5.0 by configuring the Iceberg REST catalog, enabling you to process data across your data lakes and data warehouses in a unified manner.

Here’s how querying using Jupyter Lab notebook looks like:

I continue by choosing Query with Athena. With this option, I can use serverless query capability of Amazon Athena to analyze the sales data directly within SageMaker Lakehouse. Upon selecting Query with Athena, the Query Editor launches automatically, providing an workspace where I can compose and execute SQL queries against the lakehouse. This integrated query environment offers a seamless experience for data exploration and analysis, complete with syntax highlighting and auto-completion features to enhance productivity.

I can also use Query with Redshift option to run SQL queries against the lakehouse.

SageMaker Lakehouse offers a comprehensive solution for modern data management and analytics. By unifying access to data across multiple sources, supporting a wide range of analytics and ML engines, and providing fine-grained access controls, SageMaker Lakehouse helps you make the most of your data assets. Whether you’re working with data lakes in Amazon S3, data warehouses in Amazon Redshift, or operational databases and applications, SageMaker Lakehouse provides the flexibility and security you need to drive innovation and make data-driven decisions. You can use hundreds of connectors to integrate data from various sources. Additionally, you can access and query data in-place with federated query capabilities across third-party data sources.

Now available
You can access SageMaker Lakehouse through the AWS Management Console, APIs, AWS Command Line Interface (AWS CLI), or AWS SDKs. You can also access through AWS Glue Data Catalog and AWS Lake Formation. SageMaker Lakehouse is available in US East (N. Virginia), US West (Oregon), US East (Ohio), Europe (Ireland), Europe (Frankfurt), Europe (Stockholm), Asia Pacific (Sydney), Asia Pacific (Hong Kong), Asia Pacific (Tokyo), and Asia Pacific (Singapore) AWS Regions.

For pricing information, visit the Amazon SageMaker Lakehouse pricing.

For more information on Amazon SageMaker Lakehouse and how it can simplify your data analytics and AI/ML workflows, visit the Amazon SageMaker Lakehouse documentation.

— Esra

Introducing queryable object metadata for Amazon S3 buckets (preview)

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/introducing-queryable-object-metadata-for-amazon-s3-buckets-preview/

AWS customers make use of Amazon Simple Storage Service (Amazon S3) at an incredible scale, regularly creating individual buckets that contain billions or trillions of objects! At that scale, finding the objects which meet particular criteria — objects with keys that match a pattern, objects of a particular size, or objects with a specific tag — becomes challenging. Our customers have had to build systems that capture, store, and query for this information. These systems can become complex and hard to scale, and can fall out of sync with the actual state of the bucket and the objects within.

Rich Metadata
Today we are enabling in preview automatic generation of metadata that is captured when S3 objects are added or modified, and stored in fully managed Apache Iceberg tables. This allows you to use Iceberg-compatible tools such as Amazon Athena, Amazon Redshift, Amazon QuickSight, and Apache Spark to easily and efficiently query the metadata (and find the objects of interest) at any scale. As a result, you can quickly find the data that you need for your analytics, data processing, and AI training workloads.

For video inference responses stored in S3, Amazon Bedrock will annotate the content it generates with metadata that will allow you to identify the content as AI-generated, and to know which model was used to generate it.

The metadata schema contains over 20 elements including the bucket name, object key, creation/modification time, storage class, encryption status, tags, and user metadata. You can also store additional, application-specific descriptive information in a separate table and then join it with the metadata table as part of your query.

How it Works
You can enable capture of rich metadata for any of your S3 buckets by specifying the location (an S3 table bucket and a table name) where you want the metadata to be stored. Capture of updates (object creations, object deletions, and changes to object metadata) begins right away and will be stored in the table within minutes. Each update generates a new row in the table, with a record type (CREATE, UPDATE_METADATA, or DELETE) and a sequence number. You can retrieve the historical record for a given object by running a query that orders the results by sequence number.

Enabling and Querying Metadata
I start by creating a table bucket for my metadata using the create-table-bucket command (this can also be done from the AWS Management Console or with an API call):

$ aws s3tables create-table-bucket --name jbarr-table-bucket-1 --region us-east-2
--------------------------------------------------------------------------------
|                               CreateTableBucket                              |
+-----+------------------------------------------------------------------------+
|  arn|  arn:aws:s3tables:us-east-2:123456789012:bucket/jbarr-table-bucket-1   |
+-----+------------------------------------------------------------------------+

Then I specify the table bucket (by ARN) and the desired table name by putting this JSON into a file (I’ll call it config.json):

{
  "S3TablesDestination": {
    "TableBucketArn": "arn:aws:s3tables:us-east-2:123456789012:bucket/jbarr-table-bucket-1",
    "TableName": "jbarr_data_bucket_1_table"
  }
}

And then I attach this configuration to my data bucket (the one that I want to capture metadata for):

$ aws s3tables create-bucket-metadata-table-configuration \
  --bucket jbarr-data-bucket-1 \
  --metadata-table-configuration file://./config.json \
  --region us-east-2

For testing purposes I installed Apache Spark on an EC2 instance and after a little bit of setup I was able to run queries by referencing the Amazon S3 Tables Catalog for Apache Iceberg package and adding the metadata table (as mytablebucket) to the command line:

$ bin/spark-shell \
--packages org.apache.iceberg:iceberg-spark-runtime-3.4_2.12:1.6.0 \
--jars ~/S3TablesCatalog.jar \
--master yarn \
--conf "spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions" \
--conf "spark.sql.catalog.mytablebucket=org.apache.iceberg.spark.SparkCatalog" \
--conf "spark.sql.catalog.mytablebucket.catalog-impl=com.amazon.s3tables.iceberg.S3TablesCatalog" \
--conf "spark.sql.catalog.mytablebucket.warehouse=arn:aws:s3tables:us-east-2:123456789012:bucket/jbarr-table-bucket-1"

Here is the current schema for the Iceberg table:

scala> spark.sql("describe table mytablebucket.aws_s3_metadata.jbarr_data_bucket_1_table").show(100,35)

+---------------------+------------------+-----------------------------------+
|             col_name|         data_type|                            comment|
+---------------------+------------------+-----------------------------------+
|               bucket|            string|   The general purpose bucket name.|
|                  key|            string|The object key name (or key) tha...|
|      sequence_number|            string|The sequence number, which is an...|
|          record_type|            string|The type of this record, one of ...|
|     record_timestamp|     timestamp_ntz|The timestamp that's associated ...|
|           version_id|            string|The object's version ID. When yo...|
|     is_delete_marker|           boolean|The object's delete marker statu...|
|                 size|            bigint|The object size in bytes, not in...|
|   last_modified_date|     timestamp_ntz|The object creation date or the ...|
|                e_tag|            string|The entity tag (ETag), which is ...|
|        storage_class|            string|The storage class that's used fo...|
|         is_multipart|           boolean|The object's upload type. If the...|
|    encryption_status|            string|The object's server-side encrypt...|
|is_bucket_key_enabled|           boolean|The object's S3 Bucket Key enabl...|
|          kms_key_arn|            string|The Amazon Resource Name (ARN) f...|
|   checksum_algorithm|            string|The algorithm that's used to cre...|
|          object_tags|map<string,string>|The object tags that are associa...|
|        user_metadata|map<string,string>|The user metadata that's associa...|
|            requester|            string|The AWS account ID of the reques...|
|    source_ip_address|            string|The source IP address of the req...|
|           request_id|            string|The request ID. For records that...|
+---------------------+------------------+-----------------------------------+

Here’s a simple query that shows some of the metadata for the ten most recent updates:

scala> spark.sql("SELECT key,size, storage_class,encryption_status \
  FROM mytablebucket.aws_s3_metadata.jbarr_data_bucket_1_table \
  order by last_modified_date DESC LIMIT 10").show(false)
+--------------------+------+-------------+-----------------+                   
|key                 |size  |storage_class|encryption_status|
+--------------------+------+-------------+-----------------+
|wnt_itco_2.png      |36923 |STANDARD     |SSE-S3           |
|wnt_itco_1.png      |37274 |STANDARD     |SSE-S3           |
|wnt_imp_new_1.png   |15361 |STANDARD     |SSE-S3           |
|wnt_imp_change_3.png|67639 |STANDARD     |SSE-S3           |
|wnt_imp_change_2.png|67639 |STANDARD     |SSE-S3           |
|wnt_imp_change_1.png|71182 |STANDARD     |SSE-S3           |
|wnt_email_top_4.png |135164|STANDARD     |SSE-S3           |
|wnt_email_top_2.png |117171|STANDARD     |SSE-S3           |
|wnt_email_top_3.png |55913 |STANDARD     |SSE-S3           |
|wnt_email_top_1.png |140937|STANDARD     |SSE-S3           |
+--------------------+------+-------------+-----------------+

In a real-world situation I would query the table using one of the AWS or open source analytics tools that I mentioned earlier.

Console Access
I can also set up and manage the metadata configuration for my buckets using the Amazon S3 Console by clicking the Metadata tab:

Available Now
Amazon S3 Metadata is available in preview now and you can start using it today in the US East (Ohio, N. Virginia) and US West (Oregon) AWS Regions.

Integration with AWS Glue Data Catalog is in preview, allowing you to query and visualize data—including S3 Metadata tables—using AWS Analytics services such as Amazon Athena, Amazon Redshift, Amazon EMR, and Amazon QuickSight.

Pricing is based on the number updates (object creations, object deletions, and changes to object metadata) with an additional charge for storage of the metadata table. For more pricing information, visit the S3 Pricing page.

I’m confident that you will be able to make use of this metadata in many powerful ways, and am looking forward to hearing about your use cases. Let me know what you think!

— Jeff;

New Amazon S3 Tables: Storage optimized for analytics workloads

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/new-amazon-s3-tables-storage-optimized-for-analytics-workloads/

Amazon S3 Tables give you storage that is optimized for tabular data such as daily purchase transactions, streaming sensor data, and ad impressions in Apache Iceberg format, for easy queries using popular query engines like Amazon Athena, Amazon EMR, and Apache Spark. When compared to self-managed table storage, you can expect up to 3x faster query performance and up to 10x more transactions per second, along with the operational efficiency that is part-and-parcel when you use a fully managed service.

Iceberg has become the most popular way to manage Parquet files, with thousands of AWS customers using Iceberg to query across often billions of files containing petabytes or even exabytes of data.

Table Buckets, Tables, and Namespaces
Table buckets are the third type of S3 bucket, taking their place alongside the existing general purpose and directory buckets. You can think of a table bucket as an analytics warehouse that can store Iceberg tables with various schemas. Additionally, S3 Tables deliver the same durability, availability, scalability, and performance characteristics as S3 itself, and automatically optimize your storage to maximize query performance and to minimize cost.

Each table bucket resides in a specific AWS Region and has a name that must be unique within the AWS account with respect to the region. Buckets are referenced by ARN and also have a resource policy. Finally, each bucket uses namespaces to logically group the tables in the bucket.

Tables are structured datasets stored in a table bucket. Like table buckets, they have ARNs and resource policies, and exist within one of the bucket’s namespaces. Tables are fully managed, with automatic, configurable continuous maintenance including compaction, management of aged snapshots, and removal of unreferenced files. Each table has an S3 API endpoint for storage operations.

Namespaces can be referenced from access policies in order to simplify access management.

Buckets and Tables from the Command Line
Ok, let’s dive right in, create a bucket, and put a table or two inside. I’ll use the AWS Command Line Interface (AWS CLI), but AWS Management Console and API support is also available. For conciseness, I will pipe the output of the more verbose commands through jq and show you only the most relevant values.

The first step is to create a table bucket:

$ aws s3tables create-table-bucket --name jbarr-table-bucket-2 | jq .arn
"arn:aws:s3tables:us-east-2:123456789012:bucket/jbarr-table-bucket-2"

For convenience, I create an environment variable with the ARN of the table bucket:

$ export ARN="arn:aws:s3tables:us-east-2:123456789012:bucket/jbarr-table-bucket-2"

And then I list my table buckets:

$ aws s3tables list-table-buckets | jq .tableBuckets[].arn
"arn:aws:s3tables:us-east-2:123456789012:bucket/jbarr-table-bucket-1"
"arn:aws:s3tables:us-east-2:123456789012:bucket/jbarr-table-bucket-2"

I can access and populate the table in many different ways. For testing purposes I installed Apache Spark, then invoked the Spark shell with command-line arguments to use the Amazon S3 Tables Catalog for Apache Iceberg package and to set mytablebucket to the ARN of my table.

I create a namespace (mydata) that I will use to group my tables:

scala> spark.sql("""CREATE NAMESPACE IF NOT EXISTS mytablebucket.mydata""")

Then I create a simple Iceberg table in the namespace:

spark.sql("""CREATE TABLE IF NOT EXISTS mytablebucket.mydata.table1
 (id INT,
  name STRING,
  value INT)
  USING iceberg
  """)

I use somes3tables commands to check my work:

$ aws s3tables list-namespaces --table-bucket-arn $ARN | jq .namespaces[].namespace[] 
"mydata"
$
$ aws s3tables list-tables --table-bucket-arn $ARN | jq .tables[].name
"table1"

Then I return to the Spark shell and add a few rows of data to my table:

spark.sql("""INSERT INTO mytablebucket.mydata.table1
  VALUES
  (1, 'Jeff', 100),
  (2, 'Carmen', 200),
  (3, 'Stephen', 300),
  (4, 'Andy', 400),
  (5, 'Tina', 500),
  (6, 'Bianca', 600),
  (7, 'Grace', 700)
  """)

Buckets and Tables from the Console
I can also create and work on table buckets using the S3 Console. I click Table buckets to get started:

Before creating my first bucket I click Enable integration so that I can access my table buckets from Amazon Athena, Amazon Redshift, Amazon EMR, and other AWS query engines (I can do this later if I don’t do it now):

I read the fine print and click Enable integration to create the specified IAM role and an entry in the AWS Glue Data Catalog:

After a few seconds the integration is enabled and I click Create table bucket to move ahead:

I enter a name (jbarr-table-bucket-3) and click Create table bucket:

From here I can create and use tables as I showed you earlier in the CLI section.

Table Maintenance
Table buckets take care of some important maintenance duties that would be your responsibility if you were creating and managing your own Iceberg tables. To relieve you of these duties so that you can spend more time on your table, the following maintenance operations are performed automatically:

Compaction – This process combines multiple small table objects into a larger object to improve query performance, in pursuit of a target file size that can be configured to be between 64 MiB and 512 MiB. The new object is rewritten as a new snapshot.

Snapshot Management – This process expires and ultimately removes table snapshots, with configuration options for the minimum number of snapshots to retain and the maximum age of a snapshot to retain. Expired snapshots are marked as non-current, then later deleted after a specified number of days.

Unreferenced File Removal – This process removes and deletes objects that are not referenced by any table snapshots.

Things to Know
Here are a couple of important things that you should know about table buckets and tables:

AWS Integration – S3 Tables integration with AWS Glue Data Catalog is in preview, allowing you to query and visualize data using AWS Analytics services such as Amazon Athena, Amazon Redshift, Amazon EMR, and Amazon QuickSight.

S3 API Support – Table buckets support relevant S3 API functions including GetObject, HeadObject, PutObject, and the multi-part upload operations.

Security – All objects stored in table buckets are automatically encrypted. Table buckets are configured to enforce Block Public Access.

Pricing – You pay for storage, requests, an object monitoring fee, and and fees for compaction. See the S3 Pricing page for more info.

Regions – You can use this new feature in the US East (Ohio, N. Virginia) and US West (Oregon) AWS Regions.

— Jeff;