Tag Archives: AWS Lambda

AWS Weekly Roundup: Amazon DocumentDB, AWS Lambda, Amazon EC2, and more (August 4, 2025)

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-amazon-documentdb-aws-lambda-amazon-ec2-and-more-august-4-2025/

This week brings an array of innovations spanning from generative AI capabilities to enhancements of foundational services. Whether you’re building AI-powered applications, managing databases, or optimizing your cloud infrastructure, these updates help build more advanced, robust, and flexible applications.

Last week’s launches
Here are the launches that got my attention this week:

Additional updates
Here are some additional projects, blog posts, and news items that I found interesting:

Upcoming AWS events
Check your calendars so that you can sign up for these upcoming events:

AWS re:Invent 2025 (December 1-5, 2025, Las Vegas) — AWS’s flagship annual conference offering collaborative innovation through peer-to-peer learning, expert-led discussions, and invaluable networking opportunities.

AWS Summits — Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Mexico City (August 6) and Jakarta (August 7).

AWS Community Days — Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Australia (August 15), Adria (September 5), Baltic (September 10), and Aotearoa (September 18).

Join the AWS Builder Center to learn, build, and connect with builders in the AWS community. Browse here upcoming in-person and virtual developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

– Danilo

Introducing v2 of Powertools for AWS Lambda (Java)

Post Syndicated from Philipp Page original https://aws.amazon.com/blogs/compute/introducing-v2-of-powertools-for-aws-lambda-java/

Modern applications increasingly rely on Serverless technologies such as Amazon Web Services (AWS) Lambda to provide scalability, cost efficiency, and agility. The Serverless Applications Lens for the AWS Well-Architected Framework focuses on how to design, deploy, and architect your Serverless applications to overcome some of these challenges.

Powertools for AWS Lambda is a developer toolkit that helps you implement Serverless best practices and directly translates AWS Well-Architected recommendations into actionable, developer friendly utilities. Following the community’s continued successful adoption of Powertools for AWS in Python, Java, TypeScript, and .NET, this post announces the general availability of Powertools for AWS Lambda (Java) v2 coming with major performance improvements, enhanced core utilities, and a brand-new Kafka utility.

Powertools for AWS (Java) v2 provides three updated core utilities:

  • Logging: A re-designed Java idiomatic logging module providing structured logging that streamlines log aggregation and analysis.
  • Metrics: An improved metrics experience allowing custom metrics collection using CloudWatch Embedded Metric Format (EMF).
  • Tracing: An annotation-based way to collect distributed tracing data with AWS X-Ray to visualize and analyze request flows.

Along with the updated core utilities, v2 of the developer toolkit adds two brand new features:

  • GraalVM native image support: Native image support for GraalVM across all core utilities reducing Lambda cold start times up to 75.61% (p95).
  • Kafka utility: This new utility integrates with Amazon Managed Streaming for Apache Kafka (Amazon MSK) and self-managed Kafka event sources on Lambda and allows developers to deserialize directly into Kafka native types such as ConsumerRecords.

Learn more about how to migrate to v2 in our upgrade guide.

Getting started using Powertools for AWS Lambda (Java) v2

Powertools for AWS Lambda (Java) v2 is readily accessible as a Java package on Maven Central and integrates with popular build tools such as Maven and Gradle. This post focuses on Maven-based implementation samples to help you get started quickly. Gradle examples are available for all utilities in the documentation and the examples repository.

The toolkit is compatible with Java 11 and newer versions, making sure you can use modern Java features while building Serverless applications. Examples on how to install each utility are outlined in each section of the post and complete configuration examples are also available in the Powertools documentation.

Logging

The Logging utility helps implement structured logging when running on Lambda while still using familiar Java logging libraries such as slf4j, log4j, and logback. v2 of Logging allows you to do the following:

  • Output structured JSON logs enriched with Lambda context
  • Choose the logging backend of your choice among log4j2 and logback
  • Add structured arguments to logs that get serialized into arbitrarily nested JSON objects
  • Add global log keys using the slf4j default Mapped Diagnostic Context (MDC)

To add the logging utility to your project, include it as a dependency in your Java Maven project. The following example shows how to add the log4j2 logging backend to your application:

<!-- In the dependencies section -->
<dependency>
    <groupId>software.amazon.lambda</groupId>
    <artifactId>powertools-logging-log4j</artifactId>
    <!-- Alternatively, if you wish to use the logback backend
    <artifactId>powertools-logging-logback</artifactId> 
    -->
    <version>2.1.1</version>
</dependency>
<!-- In the build plugins section -->
<plugin>
    <groupId>dev.aspectj</groupId>
    <artifactId>aspectj-maven-plugin</artifactId>
    <configuration>
        <aspectLibraries>
            <aspectLibrary>
                <groupId>software.amazon.lambda</groupId>
                <artifactId>powertools-logging</artifactId>
                <version>2.1.1</version>
            </aspectLibrary>
        </aspectLibraries>
    </configuration>
</plugin>

Create a custom JsonTemplateLayout appender in your log4j2.xml file:

<?xml version="1.0" encoding="UTF-8"?>
<Configuration>
    <Appenders>
        <Console name="JsonAppender" target="SYSTEM_OUT">
            <JsonTemplateLayout eventTemplateUri="classpath:LambdaJsonLayout.json" />
        </Console>
    </Appenders>
    <Loggers>
        <Logger name="JsonLogger" level="INFO" additivity="false">
            <AppenderRef ref="JsonAppender"/>
        </Logger>
        <Root level="info">
            <AppenderRef ref="JsonAppender"/>
        </Root>
    </Loggers>
</Configuration>

To add structured logging to your functions, apply the @Logging annotation to your Lambda handler and use the familiar slf4j Java API when writing log statements. This allows you to adopt the logging utility without major code refactoring. Powertools handles routing to the correct logging backend for you. The following example shows how to add global log keys using MDC, and add a structured entry argument to your log message:

public class App implements RequestHandler<SQSEvent, String> {
    private static final Logger log = LoggerFactory.getLogger(App.class);

    @Logging
    public String handleRequest(final SQSEvent input, final Context context) {
        // Add a global log key using Mapped Diagnostic Context MDC
        MDC.put("myCustomKey", "willBeLoggedForAllLogStatements");

        // Log a message with a structured argument (any JSON serializable Object)
        log.info("My message", entry("anotherCustomKey", Map.of("nested", "object")));

        // ... return response
    }
}

Lambda sends the following JSON-formatted output to Amazon CloudWatch Logs (note how the Java Map gets auto-serialized into a JSON object):

{
  "level": "INFO",
  "message": "My message",
  "cold_start": true,
  "function_arn": "arn:aws:lambda:us-east-1:012345678912:function:AppFunction",
  "function_memory_size": 512,
  "function_name": "AppFunction",
  "function_request_id": "0150a2a4-c5aa-4277-9345-17bad039f6c0",
  "function_version": "$LATEST",
  "sampling_rate": 0.1,
  "service": "powertools-java-sample",
  "timestamp": "2025-05-20T08:35:28.565Z",
  "myCustomKey": "willBeLoggedForAllLogStatements",
  "anotherCustomKey": {
    "nested": "object"
  }
}

Metrics

CloudWatch offers essential built-in service metrics for monitoring application throughput, error rates, and resource usage. Users also need to capture workload specific custom metrics relevant to their business use-case following AWS Well-Architected best-practices.

Powertools for AWS (Java) enables you to create custom metrics asynchronously by outputting metrics in CloudWatch EMF directly to standard output—an approach that needs no other configuration. The Lambda service sends the EMF formatted metrics to CloudWatch on your behalf.

The Metrics utility allows you to:

  • Create custom metrics asynchronously using CloudWatch EMF
  • Reduce latency by avoiding synchronous metric publishing
  • Automatically track cold starts in a custom CloudWatch metric
  • Avoid manually validating your output against the EMF specification
  • Keep you code clean by avoiding manual flushing to standard output

To add the Metrics utility to your project, add the following Maven dependency:

<!-- In the dependencies section -->
<dependency>
    <groupId>software.amazon.lambda</groupId>
    <artifactId>powertools-metrics</artifactId>
    <version>2.1.1</version>
</dependency>
<!-- In the build plugins section -->
<plugin>
    <groupId>dev.aspectj</groupId>
    <artifactId>aspectj-maven-plugin</artifactId>
    <configuration>
        <aspectLibraries>
            <aspectLibrary>
                <groupId>software.amazon.lambda</groupId>
                <artifactId>powertools-metrics</artifactId>
                <version>2.1.1</version>
            </aspectLibrary>
        </aspectLibraries>
    </configuration>
</plugin>

To add custom metrics to your Lambda function, place the @FlushMetrics annotation on your Lambda handler. The library takes care of validating and flushing your metrics to standard output before the Lambda function terminates. The following example shows how you can automatically capture a cold start metric and emit your own custom metrics:

public class App implements RequestHandler<SQSEvent, String> {
    private static final Logger log = LoggerFactory.getLogger(App.class);
    private static final Metrics metrics = MetricsFactory.getMetricsInstance();

    // This configures a default namespace and service dimension for all metrics
    @FlushMetrics(namespace = "ServerlessAirline", service = "payment", captureColdStart = true)
    public String handleRequest(final SQSEvent input, final Context context) {
        // The Metrics instance is a singleton
        metrics.addMetric("CustomMetric1", 1, MetricUnit.COUNT);

        // Publish metrics with non-default configuration options
        DimensionSet dimensionSet = new DimensionSet();
        dimensionSet.addDimension("Service", "AnotherService");
        metrics.flushSingleMetric("CustomMetric2", 1, MetricUnit.COUNT, "AnotherNamespace", dimensionSet);

        // ... return response
    }
}
AWS CloudWatch Metrics Graph View of metrics generated by Metrics utility example.

Figure 1. AWS CloudWatch Metrics Graph View

Tracing

The Tracing utility provides an annotation-based integration with X-Ray for distributed tracing with minimal configuration. Tracing allows you to:

  • Gain visibility into your own methods calls and AWS service interactions visualized in the X-Ray console
  • Automatically capture method responses and errors
  • Automatically capture Lambda cold start information as part of your traces
  • Add custom metadata to traces for more context and debugging information
  • Enable or disable tracing features through environment variables without code changes

To add the Tracing utility to your project, add the following Maven dependency:

<!-- In the dependencies section -->
<dependency>
    <groupId>software.amazon.lambda</groupId>
    <artifactId>powertools-tracing</artifactId>
    <version>2.1.1</version>
</dependency>
<!-- In the build plugins section -->
<plugin>
    <groupId>dev.aspectj</groupId>
    <artifactId>aspectj-maven-plugin</artifactId>
    <configuration>
        <aspectLibraries>
            <aspectLibrary>
                <groupId>software.amazon.lambda</groupId>
                <artifactId>powertools-tracing</artifactId>
                <version>2.1.1</version>
            </aspectLibrary>
        </aspectLibraries>
    </configuration>
</plugin>

To enable tracing in your Lambda function, annotate your Lambda handler and your custom methods that you want to trace with the @Tracing annotation. Each annotation maps to a sub-segment of your main Lambda handler in X-Ray and becomes visible in the console.

public class App implements RequestHandler<APIGatewayProxyRequestEvent, APIGatewayProxyResponseEvent> {
    private static final Logger log = LoggerFactory.getLogger(App.class);

    @Tracing
    public APIGatewayProxyResponseEvent handleRequest(final APIGatewayProxyRequestEvent input, final Context context) {
        // ... business logic
        
        // Get calling IP with tracing
        String location = getCallingIp("https://checkip.amazonaws.com");

        // ... return response
    }

    @Tracing(segmentName = "Location service")
    private String getCallingIp(String address) {
        // Implementation to get IP address
        log.info("Retrieving caller IP address");
        
        // Add custom metadata to current sub-segment
        URL url = new URL(address);
        putMetadata("getCallingIp", address);
        
        // ...
        return "127.0.0.1";
    }
}

The X-Ray console displays a generated service map when traffic begins flowing through your application. Applying the Tracing annotation to your Lambda function handler method or any other methods in the execution chain provides you with comprehensive visibility into the traffic patterns throughout your application. The following figure shows how the custom metadata added in the example is associated with the custom sub-segment.

Picture showing the generated traces in the AWS X-Ray console. Shows the custom named Location service trace along with its metadata as a JSON object.

Figure 2. AWS X-Ray waterfall trace view

Reducing Lambda cold start duration

A key feature in Powertools for AWS Lambda (Java) v2 is GraalVM native image support for all core utilities. Compiling your Lambda functions to native executables allows you to significantly reduce cold start times and memory usage. Using Powertools v2 with GraalVM allows you to reduce cold starts up to 75.61% (p95) compared to using the managed Java runtime. The following benchmark compares the cold start times of an application using all core utilities (logging, metrics, tracing) on the managed java21 runtime as compared to the Lambda provided.al2023 runtime running a GraalVM compiled native image (go to the supported Lambda runtimes):

Environment p95 (ms) Min (ms) Avg (ms) Max (ms) Max Memory (MB) N
Powertools for AWS (Java) v2: JVM 1682.92 1224.55 1224.55 2229.81 205.04 234
Powertools for AWS (Java) v2: GraalVM 542.86 404.92 504.77 752.85 93.46 369

This improvement is particularly valuable for latency-sensitive applications and functions that scale frequently. Check out a full working example on GitHub.

Lambda MSK Event Source Mapping Integration

The new Kafka utility introduced with Powertools for AWS Lambda (Java) v2 streamlines working with the Lambda MSK Event Source Mapping (ESM) and self-managed Kafka event sources. It provides a familiar experience for developers working with Apache Kafka by allowing direct conversion from Lambda events to Kafka’s native types. The key features include:

  • Direct deserialization into Kafka ConsumerRecords<K, V> objects while using the Lambda-native RequestHandler interface
  • Support for deserializing JSON, Avro, and Protobuf encoded records for key and value fields with and without usage of a Schema Registry when producing the messages

To add the Kafka utility to your project, include the powertools-kafka library as a Maven dependency in your pom.xml:

<!-- In the dependencies section -->
<dependency>
    <groupId>software.amazon.lambda</groupId>
    <artifactId>powertools-kafka</artifactId>
    <version>2.1.1</version>
</dependency>
<!-- Kafka clients dependency - compatibility works for >= 3.0.0 -->
<dependency>
    <groupId>org.apache.kafka</groupId>
    <artifactId>kafka-clients</artifactId>
    <version>4.0.0</version>
</dependency>

Use the @Deserialization annotation on your Lambda handler to deserialize messages as native Kafka ConsumerRecords. Make sure to specify the deserializer type. The following example shows how to deserialize Avro encoded record values with String keys. As in a regular Lambda handler, declare the input type to your function in the RequestHandler generic parameters and the utility discovers the deserialization types automatically. The AvroProduct class in the following example is an auto-generated Java class using the Java org.apache.avro.avro library.

public class App implements RequestHandler<ConsumerRecords<String, AvroProduct>, Void> {
    private static final Logger log = LoggerFactory.getLogger(App.class);

    @Deserialization(type = DeserializationType.KAFKA_AVRO)
    public Void handleRequest(ConsumerRecords<String, AvroProduct> consumerRecords, Context context) {
        log.info("Deserialized {} records.", consumerRecords.records().size()); 

        // ... Business logic 
        
        return null;
    }
}

Conclusion

Powertools for AWS Lambda (Java) v2 represents the next evolution in the toolkit for building robust, observable, and high-performing Serverless applications. Throughout this post, we’ve explored the enhanced core observability utilities with their new features, the performance gains through GraalVM native image support, and the new Kafka utility that supports using familiar Kafka patterns when working on Lambda.

Powertools also offers more utilities to handle common Serverless design patterns. Each utility is designed with the same principles of clarity and minimal overhead.To learn more:

  1. Visit the documentation for detailed guides and examples
  2. Try the sample applications
  3. Join the community on GitHub to share your experience and get help

Your next Serverless application awaits with Powertools for AWS Lambda (Java) v2. We would love to hear your feedback!

Streamlining AWS Serverless workflows: From AWS Lambda orchestration to AWS Step Functions

Post Syndicated from Diego Casas original https://aws.amazon.com/blogs/compute/streamlining-aws-serverless-workflows-from-aws-lambda-orchestration-to-aws-step-functions/

This blog post discusses the AWS Lambda as orchestrator anti-pattern and how to redesign serverless solutions using AWS Step Functions with native integrations.

Step Functions is a serverless workflow service that you can use to build distributed applications, automate processes, orchestrate microservices, and create data and machine learning (ML) pipelines. Step Functions provides native integrations with over 200 AWS services in addition to external third-party APIs. You can use these integrations to deploy production-ready solutions with less effort, reducing code complexity, improving long-term maintainability, and minimizing technical debt when operating at scale.

The Lambda as orchestrator anti-pattern

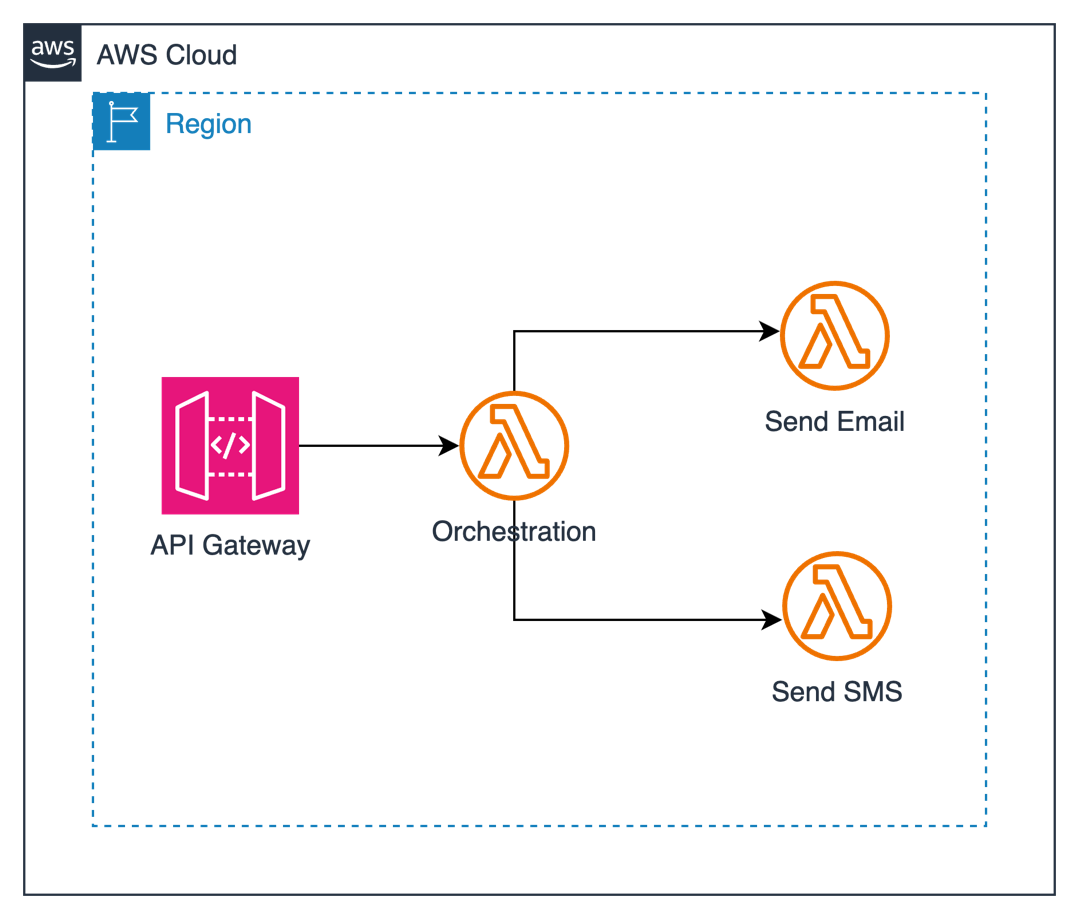
Let’s examine a common anti-pattern: using a Lambda function as an orchestrator for message distribution across multiple channels. Consider this real-world scenario where a system needs to send notifications through SMS or email channels based on user preferences, as shown in the following diagram.

The payload examples for this scenario are:

  1. Send SMS only:
    {
        "body": {
            "channel": "sms",
            "message": "Hello from AWS Lambda!",
            "phoneNumber": "+1234567890",
            "metadata": {
                "priority": "high",
                "category": "notification"
            }
        }
    }

  2. Send email only:
    {
        "body": {
            "channel": "email",
            "message": "Hello from AWS Lambda!",
            "email": {
                "to": "[email protected]",
                "subject": "Test Notification",
                "from": "[email protected]"
            },
            "metadata": {
                "priority": "normal",
                "category": "notification"
            }
        }
    }

  3. Send both SMS and email:
    {
        "body": {
            "channel": "both",
            "message": "Hello from AWS Lambda!",
            "phoneNumber": "+1234567890",
            "email": {
                "to": "[email protected]",
                "subject": "Test Notification",
                "from": "[email protected]"
            },
            "metadata": {
                "priority": "high",
                "category": "notification"
            }
        }
    }

Here’s how it typically starts—with a Lambda function acting as an orchestrator:

import boto3
import json
# Initialize Lambda client
# You can specify region if needed: boto3.client('lambda', region_name='us-east-1')
lambda_client = boto3.client('lambda')
def lambda_handler(event, context):
    try:
        # Parse the incoming event
        body = json.loads(event['body'])
        
        # Validate required fields
        if 'channel' not in body:
            return {
                'statusCode': 400,
                'body': json.dumps('Missing channel parameter')
            }
        
        if 'message' not in body:
            return {
                'statusCode': 400,
                'body': json.dumps('Missing message content')
            }
        
        if body['channel'] == 'both':
            # Invoke SMS Lambda function
            lambda_client.invoke(
                FunctionName='send-sns',
                InvocationType='Event',
                Payload=json.dumps(body)
            )
            
            # Invoke Email Lambda function
            lambda_client.invoke(
                FunctionName='send-email',
                InvocationType='Event',
                Payload=json.dumps(body)
            )
        else:
            # Validate channel value
            if body['channel'] not in ['sms', 'email']:
                return {
                    'statusCode': 400,
                    'body': json.dumps('Invalid channel specified')
                }
            
            # Invoke function based on specified channel
            function_name = 'send-sns' if body['channel'] == 'sms' else 'send-email'
            lambda_client.invoke(
                FunctionName=function_name,
                InvocationType='Event',
                Payload=json.dumps(body)
            )
        
        return {
            'statusCode': 200,
            'body': json.dumps('Messages sent successfully')
        }
        
    except json.JSONDecodeError:
        return {
            'statusCode': 400,
            'body': json.dumps('Invalid JSON in request body')
        }
    except Exception as e:
        return {
            'statusCode': 500,
            'body': json.dumps(f'Error: {str(e)}')
        }

This approach has the following problems:

  • Complex error handling: The orchestrator needs to manage errors from multiple function invocations.
  • Tight coupling: Functions are directly dependent on each other.
  • Limited execution time: The orchestrator Lambda function continues running while sub Lambda functions execute. This could lead to the orchestrator Lambda function timing out.
  • Idle resources: Because the orchestrator Lambda function is sitting idle waiting for returns from other Lambda functions, in this case, the user is now paying for idle resources.

Rearchitecting with Step Functions

You can rebuild the logic using Step Functions and Amazon States Language to replace the Lambda orchestrator function. You can use the Choice state in Amazon States Language to define logical conditions to follow a specific path. This approach reduces code maintenance complexity because you define the conditions using Amazon States Language. You can also use it to to extend the functionality with minimal changes to the codebase.

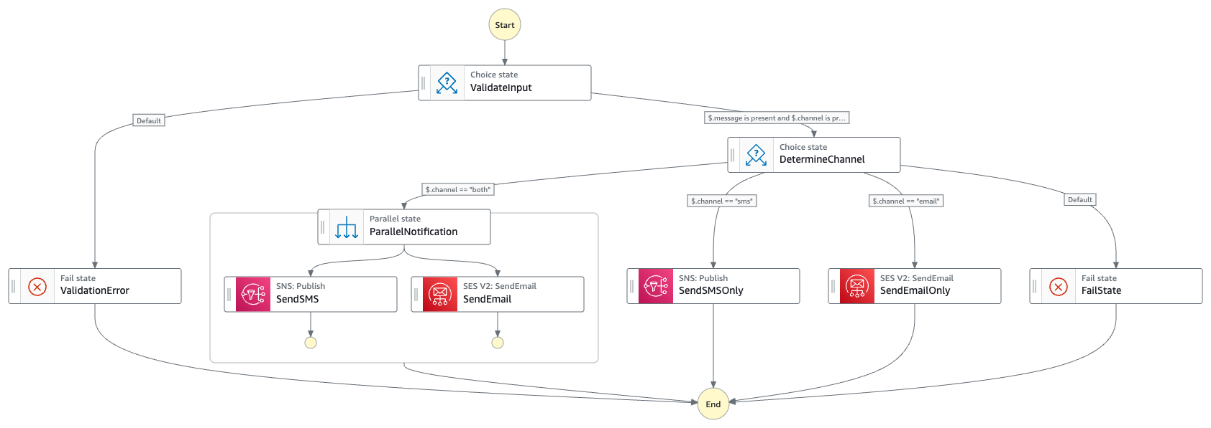
The following Step Functions workflow diagram shows the rearchitected version of the previous Orchestrator Lambda function:

The following Amazon State Language represents the workflow:

{
  "Comment": "Multi-channel notification workflow",
  "StartAt": "ValidateInput",
  "States": {
    "ValidateInput": {
      "Type": "Choice",
      "Choices": [
        {
          "And": [
            {
              "Variable": "$.message",
              "IsPresent": true
            },
            {
              "Variable": "$.channel",
              "IsPresent": true
            }
          ],
          "Next": "DetermineChannel"
        }
      ],
      "Default": "ValidationError"
    },
    "ValidationError": {
      "Type": "Fail",
      "Error": "ValidationError",
      "Cause": "Required fields missing: message and/or channel"
    },
    "DetermineChannel": {
      "Type": "Choice",
      "Choices": [
        {
          "Variable": "$.channel",
          "StringEquals": "both",
          "Next": "ParallelNotification"
        },
        {
          "Variable": "$.channel",
          "StringEquals": "sms",
          "Next": "SendSMSOnly"
        },
        {
          "Variable": "$.channel",
          "StringEquals": "email",
          "Next": "SendEmailOnly"
        }
      ],
      "Default": "FailState"
    },
    "ParallelNotification": {
      "Type": "Parallel",
      "Branches": [
        {
          "StartAt": "SendSMS",
          "States": {
            "SendSMS": {
              "Type": "Task",
              "Resource": "arn:aws:states:::sns:publish",
              "Parameters": {
                "Message.$": "$.message",
                "PhoneNumber.$": "$.phoneNumber"
              },
              "End": true
            }
          }
        },
        {
          "StartAt": "SendEmail",
          "States": {
            "SendEmail": {
              "Type": "Task",
              "Parameters": {
                "FromEmailAddress.$": "$.email.from",
                "Destination": {
                  "ToAddresses.$": "States.Array($.email.to)",
                  "CcAddresses.$": "States.ArrayGetItem(States.JsonToString($.email.cc), $)",
                  "BccAddresses.$": "States.ArrayGetItem(States.JsonToString($.email.bcc), $)"
                },
                "Content": {
                  "Simple": {
                    "Subject": {
                      "Data.$": "$.email.subject",
                      "Charset": "UTF-8"
                    },
                    "Body": {
                      "Text": {
                        "Data.$": "$.message",
                        "Charset": "UTF-8"
                      },
                      "Html": {
                        "Data.$": "$.email.htmlBody",
                        "Charset": "UTF-8"
                      }
                    }
                  }
                },
                "ReplyToAddresses.$": "States.Array($.email.replyTo)",
                "EmailTags": [
                  {
                    "Name": "channel",
                    "Value": "email"
                  },
                  {
                    "Name": "messageType",
                    "Value.$": "$.email.messageType"
                  }
                ],
                "ConfigurationSetName.$": "$.email.configurationSet",
                "ListManagementOptions": {
                  "ContactListName.$": "$.email.contactList",
                  "TopicName.$": "$.email.topic"
                }
              },
              "Resource": "arn:aws:states:::aws-sdk:sesv2:sendEmail",
              "End": true
            }
          }
        }
      ],
      "End": true
    },
    "SendSMSOnly": {
      "Type": "Task",
      "Resource": "arn:aws:states:::sns:publish",
      "Parameters": {
        "Message.$": "$.message",
        "PhoneNumber.$": "$.phoneNumber"
      },
      "End": true
    },
    "SendEmailOnly": {
      "Type": "Task",
      "Parameters": {
        "FromEmailAddress.$": "$.email.from",
        "Destination": {
          "ToAddresses.$": "States.Array($.email.to)"
        },
        "Content": {
          "Simple": {
            "Subject": {
              "Data.$": "$.email.subject",
              "Charset": "UTF-8"
            },
            "Body": {
              "Text": {
                "Data.$": "$.message",
                "Charset": "UTF-8"
              },
              "Html": {
                "Data.$": "$.email.htmlBody",
                "Charset": "UTF-8"
              }
            }
          }
        }
      },
      "Resource": "arn:aws:states:::aws-sdk:sesv2:sendEmail",
      "End": true
    },
    "FailState": {
      "Type": "Fail",
      "Cause": "Invalid channel specified"
    }
  }
}

This Step Functions implementation offers several advantages:

  • Native service integration: Direct integration with Amazon Simple Notification Service (Amazon SNS), Amazon Simple Email Service (Amazon SES), Amazon DynamoDB, and Amazon CloudWatch eliminates the need for wrapper Lambda functions
  • Visual workflow: The execution flow is visible and maintainable through the AWS Management Console
  • Built-in error handling: Retry policies and error states can be defined declaratively
  • Parallel execution: The Parallel state handles multiple channel delivery efficiently
  • Simplified logic: The Choice state replaces complex if-else statements
  • Centralized data flow: Input and output are managed consistently across states
  • Enhanced workflow duration capabilities: Step Functions Standard workflows support executions that run for up to one year, compared to the 15-minute maximum execution time for Lambda functions

Comparing Lambda function as orchestrator to Step Functions

The summary of different features implemented on Lambda function as orchestrator and Step Functions is reflected in the following table:

Feature Lambda function as orchestrator Step Functions
Orchestration logic Implemented in Python with nested if-else statements. Defined declaratively using the Choice state
Multi-channel delivery Sequential function invocations. Parallel execution using function’s logic. Parallel execution using the Parallel state
Service integration Requires SDK calls or separate Lambda functions. Direct integration with AWS services (Amazon SNS, DynamoDB)
Error handling Custom try-except blocks in Python. Built-in error states and retry policies
Data persistance Custom code to interact with DynamoDB. Native DynamoDB integration with putItem task
Metrics logging Custom code to call CloudWatch. CloudWatch Metrics SDK integration

Implementation considerations

Review the following considerations when re-architecting a Lambda function orchestrator to Step Functions:

  • State machine type: Choose between Standard (up to 1 year runtime) and Express (up to 5 minutes) workflows based on your needs.
  • Input/output management: Parameters manipulation reduces the development effort and give flexible alternatives to implement the workflow:
    • Parameters: Selects specific input fields to pass to the next state
    • ResultSelector: Filters the state response to include only relevant fields
    • ResultPath: Stores the processed result in a specific path of the state input
    • OutputPath: Determines what data passes to the next state
      A code snippet for these features is:

      {
          "ProcessOrder": {
              "Type": "Task",
              "Resource": "arn:aws:states:::lambda:invoke",
              "Parameters": {
                  "FunctionName": "ProcessOrderFunction",
                  "Payload": {
                      "orderId.$": "$.orderId",
                      "customerId.$": "$.customerId"
                  }
              },
              "ResultSelector": {
                  "orderStatus.$": "$.Payload.status",
                  "processedDate.$": "$.Payload.timestamp"
              },
              "ResultPath": "$.orderProcessing",
              "OutputPath": "$.orderProcessing",
              "Next": "NotifyCustomer"
          }
      }

  • Error handling: Implement retry policies and catch errors at both the task and state machine levels.
  • Monitoring: Set up CloudWatch logs and metrics for your state machine to track executions and performance.

Benefits of using Step Functions

Using Step Functions for rearchitecting scenarios bring the following benefits:

  • Reduced code complexity: The business logic is now defined in Amazon States Language rather than distributed across multiple Lambda functions.
  • Improved maintainability: Developers can make workflow changes by modifying the Amazon States Language, often modifying several Lambda functions.
  • Native AWS service integrations: Step Functions offers direct integrations with over 200 AWS services, which you can use to connect and coordinate AWS resources without writing custom integration code.
  • Cost optimization: By using direct service integrations, there are fewer Lambda invocations and reduced costs.
  • Long-running processes: Step Functions can manage workflows that run for up to a year, beyond the 15-minute limit for Lambda functions.

Conclusion

Rearchitecting Lambda-based applications with Step Functions can significantly improve maintainability, scalability, and operational efficiency. By moving orchestration logic into Step Functions and using its native service integrations, you can create more robust and manageable serverless applications.

While this post focused on a message distribution workflow, the principles apply to many serverless architectures. As you develop your applications, consider how Step Functions can help you build more resilient and scalable solutions.

To learn more about serverless architectures visit Serverless Land.

How Zapier runs isolated tasks on AWS Lambda and upgrades functions at scale

Post Syndicated from Anton Aleksandrov original https://aws.amazon.com/blogs/architecture/how-zapier-runs-isolated-tasks-on-aws-lambda-and-upgrades-functions-at-scale/

Zapier is a leading no-code automation provider whose customers use their solution to automate workflows and move data across over 8,000 applications such as Slack, Salesforce, Asana, and Dropbox. Zapier runs these automations through integrations called Zaps, which are implemented using a serverless architecture running on Amazon Web Services (AWS). Each Zap is powered by an AWS Lambda function.

In this post, you’ll learn how Zapier has built their serverless architecture focusing on three key aspects: using Lambda functions to build isolated Zaps, operating over a hundred thousand Lambda functions through Zapier’s control plane infrastructure, and enhancing security posture while reducing maintenance efforts by introducing automated function upgrades and cleanup workflows into their platform architecture.

Architecting a secure and isolated runtime environment

Zaps created by Zapier’s users implement tenant-specific business logic, hence they require cross-tenant compute isolation. Code implementing one Zap can’t share an execution environment with code implementing another Zap. Moreover, the same Zap type used by two different tenants can’t share execution environments as well.

To achieve the required level of isolation, Zapier’s engineering team adopted AWS Lambda, a serverless compute service that runs code in response to events and automatically manages cloud compute resources. Minimal operational overhead, built-in high availability, automated scaling, high level of isolation, and pay-per-use model made Lambda a great fit for this use case. Currently, Zapier’s architecture is running over a hundred thousand Lambda functions to support their customer’s integration workflows.

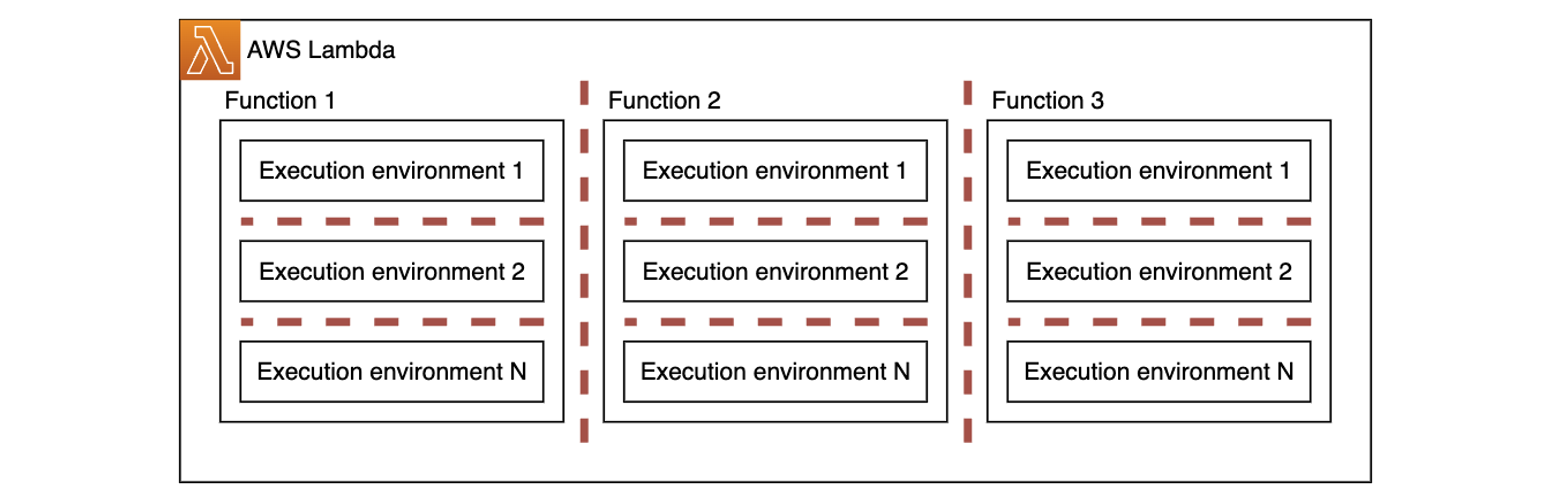
Because they’re powered by the open source Firecracker microVMs, each function is completely isolated from the others. Moreover, each execution environment belonging to the same function (sometimes referred to as function instances) is also isolated from other execution environments. The following architecture topology diagram uses red lines to represent isolation boundaries. Each execution environment of every function is isolated from its peers and is getting its own virtual resources such as disk, memory, and CPU. For more details, read Security in AWS Lambda.

Isolation boundary

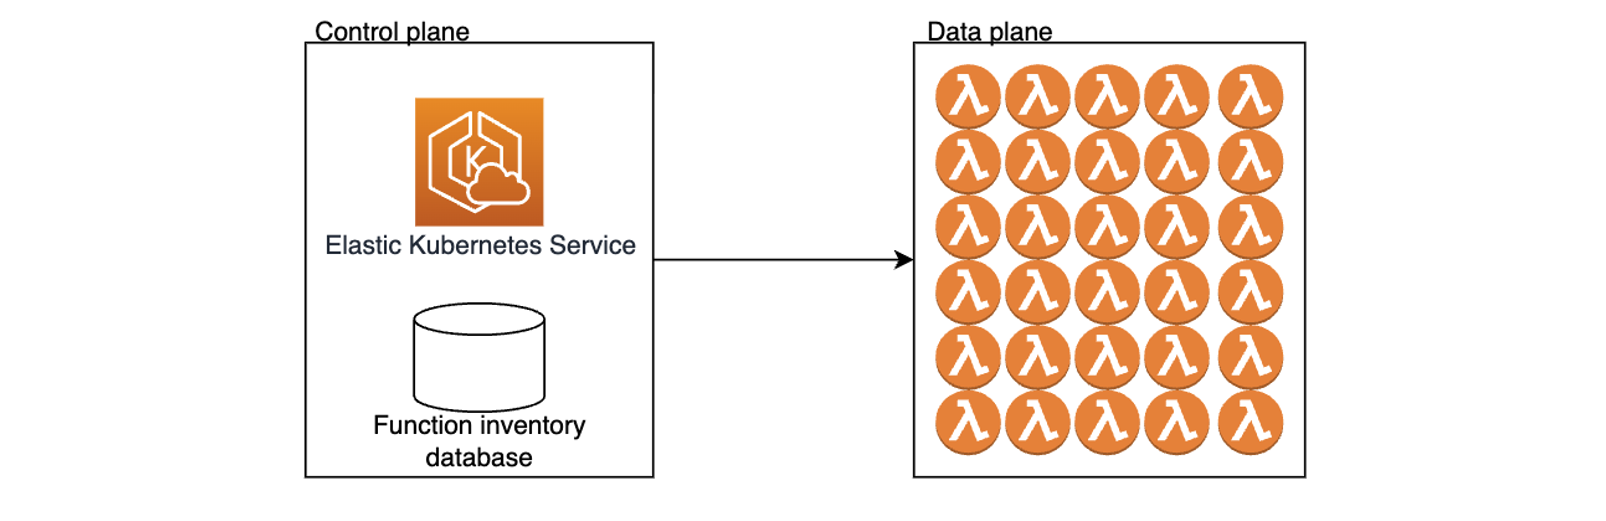
Zapier’s control plane is architected using Amazon Elastic Kubernetes Service (Amazon EKS). A designated database is used to maintain the up-to-date function inventory. Whenever a user creates a new Zap, the control plane creates a corresponding Lambda function and stores a reference in the inventory database. When a Zap is triggered, the control plane retrieves information about a relevant Lambda function and invokes it to facilitate the integration workflow, as illustrated in the following diagram.

Control and Data planes

Understanding the runtime deprecation process

When building architectures using the traditional non-serverless compute, cloud engineers are the ones responsible for keeping operating systems and software on their compute instances up to date and applying security and maintenance patches. With serverless architectures and Lambda functions, security patches and minor runtime upgrades are handled by AWS automatically, which means customers can focus on delivering business value instead of the undifferentiated heavy lifting of infrastructure management.

When a major Lambda managed runtime version reaches end-of-life, AWS initiates a deprecation process through the AWS Health Dashboard and direct email communications to affected customers. Because deprecated runtimes eventually lose access to security updates and support, organizations must upgrade to supported runtime versions to avoid potential security risks. Read more about the shared responsibility model, runtime use after deprecation, and receiving runtime deprecation notifications.

As Zapier’s user base and architectural complexity – and consequently the number of Zaps – were growing, keeping all functions on the most up-to-date major runtime versions became a laborious task. Top contributing factors were:

  • High number of functions. At its peak, the Zapier platform was running Zaps using hundreds of thousands of unique Lambda functions. Approximately 35% of these functions were using a runtime that was scheduled for deprecation in the next 12 months.
  • Zapier architected their data plane environment to be ephemeral – the control plane creates and deletes Lambda functions on demand and manages their lifecycle dynamically. Identifying a specific owner for each affected function wasn’t always straightforward.
  • Security is paramount at Zapier and upgrading affected functions runtime prior to the deprecation date was an absolute must. At no point could Zapier functions use runtimes after their deprecation date. This was a task which required extra resources.
  • The upgrade process shouldn’t have had any impact on the end customer experience. At no point should customer experience be affected.

With a short runway, high-volume workload, and the strict requirements of not impacting customer experience, Zapier’s Platform Engineering team took on this challenge of maintaining high security posture in their platform architecture.

Applying the solution

The solution had three work streams:

  1. Reducing the risk by analyzing the architecture and identifying and cleaning up unused functions.
  2. Prioritizing upgrades by identifying the most critical and impactful functions.
  3. Empowering engineering teams with automated tools and knowledge to streamline the upgrade process in future.

Identify and clean up unused functions

The first step in streamlining the upgrade process was identifying and removing unused functions. This reduced the total number of functions in Zapier’s architecture that required upgrades, eliminating unnecessary work for the team.

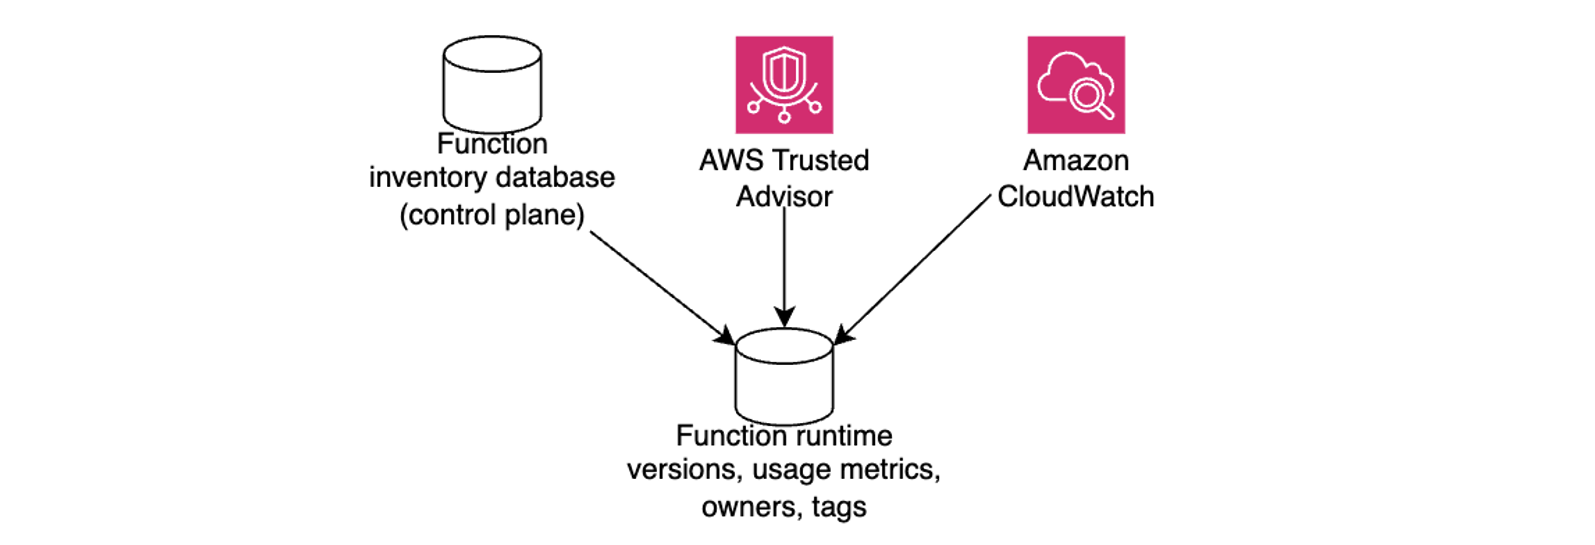
Zapier started by augmenting the function inventory with runtime information using AWS Trusted Advisor and Amazon Cloud Intelligence Trusted Advisor dashboards, as illustrated in the following diagram.

Gathering data

This meant the team could build a detailed inventory of functions that were running on soon-to-be deprecated runtimes. Using Amazon CloudWatch, Zapier’s platform team started to monitor metrics such as number of invocations. They identified which functions were active, which functions weren’t used for an extended period, and which functions didn’t have an active owner and could be removed.

One of the primary mechanisms for ownership validation within the organization was using resource tags. Functions that were active, but didn’t have clear ownership, were flagged for additional review before removal. Functions that were confirmed as unused or didn’t have an active owner were marked for deletion. Removing such functions allowed Zapier to significantly simplify their architecture and reduce the number of functions that had to be upgraded.

Prioritizing upgrades

With a smaller volume of functions to upgrade, Zapier’s platform team prioritized function upgrades based on usage patterns, criticality, and potential customer impact. Three primary prioritization categories were:

  • Customer-facing functions – Any functions directly involved in executing user Zaps were marked as high priority. These had to be upgraded first to avoid service disruptions.
  • Backend infrastructure functions – Internal functions that supported system operations were evaluated based on their importance to platform stability.
  • High-volume functions – Functions with the highest execution frequency were prioritized because upgrading them would have the greatest impact on reducing operational risk.

Using these factors, Zapier’s platform team has created an upgrade roadmap, ensuring that critical assets were addressed first while minimizing potential disruptions.

Refer to Retrieve data about Lambda functions that use a deprecated runtime in the Lambda Developer Guide to learn how to identify most commonly and most frequently used Lambda functions in your serverless architecture.

Empowering engineering teams with automated tools and knowledge

To ensure a smooth and efficient upgrade process across their serverless architecture, Zapier’s team empowered engineering teams with clear guidelines and automated solutions. The platform incorporated two main approaches: Terraform-managed functions and a custom-built Lambda runtime canary tool. Implementing and adopting these tools and practices resulted in reducing the number of functions using soon-to-be deprecated runtimes by 95%.

For functions managed through infrastructure-as-code (IaC), Zapier’s team developed standardized Terraform modules that specified supported runtime versions. Development teams implemented these modules in their configurations:

resource "aws_lambda_function" "example" {
    runtime = "python3.13"  # Updated to supported runtime
}

After applying the new module version, teams validated changes by testing the new runtime in staging environments and monitoring Terraform plan outputs to ensure proper runtime version updates.

To efficiently manage most Lambda functions in their architecture, Zapier developed the Lambda runtime canary tool suite. Using this solution, they automated the runtime upgrade process for thousands of active Lambda functions with minimal manual intervention. The tool suite implements several key features:

  • Architected for gradual traffic shifting with the Lambda built-in routing mechanism through function version and aliasing. The tool can gradually shift traffic distribution from an old to a new function version. During this gradual traffic shift, the system monitors CloudWatch metrics for errors and automatically rolls back if error rates exceed acceptable thresholds.
  • Optimistic upgrade strategy implements direct upgrades for infrequently used functions using a flag value stored in a cache to detect potential issues during the first post-upgrade invocation. If this invocation fails, the control plane retries it using the previous function version. If the retried invocation succeeds, Zapier’s control plane initiates a rollback, assuming the error is most likely due to the runtime upgrade. After rollback, it will log the error and alert relevant stakeholders.
  • Integration with existing infrastructure uses an administrative interface and task queue for automated traffic shifting. A database ledger maintains tracking of function states and rollback information.
  • Operational controls provide manual rollback capabilities and implement centralized control switches for process management. After a function was upgraded to a new runtime and no rollback activity was detected within a set time period, an automated pruning task cleans up older versions.

Zapier’s Lambda canary tool, through its integration of gradual traffic shifting, real-time CloudWatch monitoring, and automated rollback mechanisms, established a sustainable framework for managing runtime upgrades across their serverless architecture. This approach not only automated the upgrade process and minimized operational risks but also created a scalable solution that provides continuous runtime upgrades, preventing the use of deprecated runtimes at any point. By allowing continuous function runtime updates with minimal disruption to end user experience, Zapier maintains security and stability while requiring minimal manual intervention. This framework efficiently manages their growing serverless infrastructure, providing both security and operational efficiency for future runtime updates.

Conclusion

In this post, you’ve learned how Zapier architected their software-as-a-service (SaaS) platform to provide secure, isolated execution environments using AWS Lambda and Amazon EKS, enabling their customers to create hundreds of thousands of Zaps. You’ve learned how Zapier’s team implemented the function runtime upgrade process at scale and reduced the number of functions running on soon-to-be deprecated runtimes by 95%. You’ve seen best practices that were established and techniques that helped Zapier to keep high security posture without impacting customer experience.

Use the following links to learn more about Lambda runtimes and upgrading your functions to the latest runtime versions:


About the authors

AWS Weekly Roundup: Kiro, AWS Lambda remote debugging, Amazon ECS blue/green deployments, Amazon Bedrock AgentCore, and more (July 21, 2025)

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-kiro-aws-lambda-remote-debugging-amazon-ecs-blue-green-deployments-amazon-bedrock-agentcore-and-more-july-21-2025/

I’m writing this as I depart from Ho Chi Minh City back to Singapore. Just realized what a week it’s been, so let me rewind a bit. This week, I tried my first Corne keyboard, wrapped up rehearsals for AWS Summit Jakarta with speakers who are absolutely raising the bar, and visited Vietnam to participate as a technical keynote speaker in AWS Community Day Vietnam, an energetic gathering of hundreds of cloud practitioners and AWS enthusiasts who shared knowledge through multiple technical tracks and networking sessions.

What I presented was a keynote titled “Reinvent perspective as modern developers”, featuring serverless, containers, and how we can cut the learning curves and be more productive with Amazon Q Developer and Kiro. I got a chance to discuss with a couple of AWS Community Builders and community developers, who shared how Amazon Q Developer actually addressed their challenges on building applications, with several highlighting significant productivity improvements and smoother learning curves in their cloud development journeys.

As I head back to Singapore, I’m carrying with me not just memories of delicious cà phê sữa đá (iced milk coffee), but also fresh perspectives and inspirations from this vibrant community of cloud innovators.

Introducing Kiro
One of the highlights from last week was definitely Kiro, an AI IDE that helps you deliver from concept to production through a simplified developer experience for working with AI agents. Kiro goes beyond “vibe coding” with features like specs and hooks that help get prototypes into production systems with proper planning and clarity.

Join the waitlist to get notified when it becomes available.

Last week’s AWS Launches
In other news, last week we had AWS Summit in New York, where we released several services. Here are some launches that caught my attention:

Console to IDE Integration

ECS Blue-Green Deployments

AWS Free Tier Enhanced Benefits

  • Monitor and debug event-driven applications with new Amazon EventBridge logging — Amazon EventBridge now provides enhanced logging capabilities that offer comprehensive event lifecycle tracking with detailed information about successes, failures, and status codes. This new observability feature addresses microservices and event-driven architecture monitoring challenges by providing visibility into the complete event journey.

EventBridge Enhanced Logging

S3 Vectors Overview

  • Amazon EKS enables ultra-scale AI/ML workloads with support for 100k nodes per cluster — Amazon EKS now supports up to 100,000 worker nodes in a single cluster, enabling customers to scale up to 1.6 million AWS Trainium accelerators or 800K NVIDIA GPUs. This industry-leading scale empowers customers to train trillion-parameter models and advance AGI development while maintaining Kubernetes conformance and familiar developer experience.

EKS Ultra-Scale Performance Improvements

From AWS Builder Center
In case you missed it, we just launched AWS Builder Center and integrated community.aws. Here are my top picks from the posts:

Upcoming AWS events
Check your calendars and sign up for upcoming AWS and AWS Community events:

  • AWS re:Invent – Register now to get a head start on choosing your best learning path, booking travel and accommodations, and bringing your team to learn, connect, and have fun. If you’re an early-career professional, you can apply to the All Builders Welcome Grant program, which is designed to remove financial barriers and create diverse pathways into cloud technology.
  • AWS Builders Online Series – If you’re based in one of the Asia Pacific time zones, join and learn fundamental AWS concepts, architectural best practices, and hands-on demonstrations to help you build, migrate, and deploy your workloads on AWS.
  • AWS Summits — Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Taipei (July 29), Mexico City (August 6), and Jakarta (June 26–27).
  • AWS Community Days — Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Singapore (August 2), Australia (August 15), Adria (September 5), Baltic (September 10), and Aotearoa (September 18).

You can browse all upcoming AWS led in-person and virtual developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Donnie

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!


Join Builder ID: Get started with your AWS Builder journey at builder.aws.com

Simplify serverless development with console to IDE and remote debugging for AWS Lambda

Post Syndicated from Micah Walter original https://aws.amazon.com/blogs/aws/simplify-serverless-development-with-console-to-ide-and-remote-debugging-for-aws-lambda/

Today, we’re announcing two significant enhancements to AWS Lambda that make it easier than ever for developers to build and debug serverless applications in their local development environments: console to IDE integration and remote debugging. These new capabilities build upon our recent improvements to the Lambda development experience, including the enhanced in-console editing experience and the improved local integrated development environment (IDE) experience launched in late 2024.

When building serverless applications, developers typically focus on two areas to streamline their workflow: local development environment setup and cloud debugging capabilities. While developers can bring functions from the console to their IDE, they’re looking for ways to make this process more efficient. Additionally, as functions interact with various AWS services in the cloud, developers want enhanced debugging capabilities to identify and resolve issues earlier in the development cycle, reducing their reliance on local emulation and helping them optimize their development workflow.

Console to IDE integration

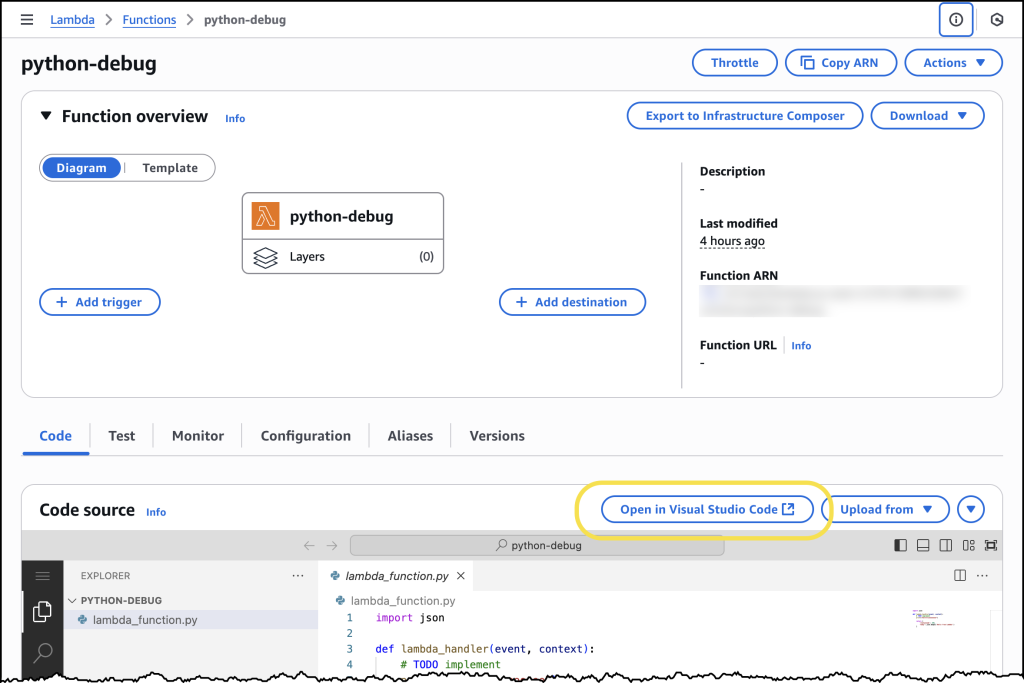
To address the first challenge, we’re introducing console to IDE integration, which streamlines the workflow from the AWS Management Console to Visual Studio Code (VS Code). This new capability adds an Open in Visual Studio Code button to the Lambda console, enabling developers to quickly move from viewing their function in the browser to editing it in their IDE, eliminating the time-consuming setup process for local development environments.

The console to IDE integration automatically handles the setup process, checking for VS Code installation and the AWS Toolkit for VS Code. For developers that have everything already configured, choosing the button immediately opens their function code in VS Code, so they can continue editing and deploy changes back to Lambda in seconds. If VS Code isn’t installed, it directs developers to the download page, and if the AWS Toolkit is missing, it prompts for installation.

To use console to IDE, look for the Open in VS Code button in either the Getting Started popup after creating a new function or the Code tab of existing Lambda functions. After selecting, VS Code opens automatically (installing AWS Toolkit if needed). Unlike the console environment, you now have access to a full development environment with integrated terminal – a significant improvement for developers who need to manage packages (npm install, pip install), run tests, or use development tools like linters and formatters. You can edit code, add new files/folders, and any changes you make will trigger an automatic deploy prompt. When you choose to deploy, the AWS Toolkit automatically deploys your function to your AWS account.

Screenshot showing Console to IDE

Remote debugging

Once developers have their functions in their IDE, they can use remote debugging to debug Lambda functions deployed in their AWS account directly from VS Code. The key benefit of remote debugging is that it allows developers to debug functions running in the cloud while integrated with other AWS services, enabling faster and more reliable development.

With remote debugging, developers can debug their functions with complete access to Amazon Virtual Private Cloud (VPC) resources and AWS Identity and Access Management (AWS IAM) roles, eliminating the gap between local development and cloud execution. For example, when debugging a Lambda function that interacts with an Amazon Relational Database Service (Amazon RDS) database in a VPC, developers can now debug the execution environment of the function running in the cloud within seconds, rather than spending time setting up a local environment that might not match production.

Getting started with remote debugging is straightforward. Developers can select a Lambda function in VS Code and enable debugging in seconds. AWS Toolkit for VS Code automatically downloads the function code, establishes a secure debugging connection, and enables breakpoint setting. When debugging is complete, AWS Toolkit for VS Code automatically cleans up the debugging configuration to prevent any impact on production traffic.

Let’s try it out

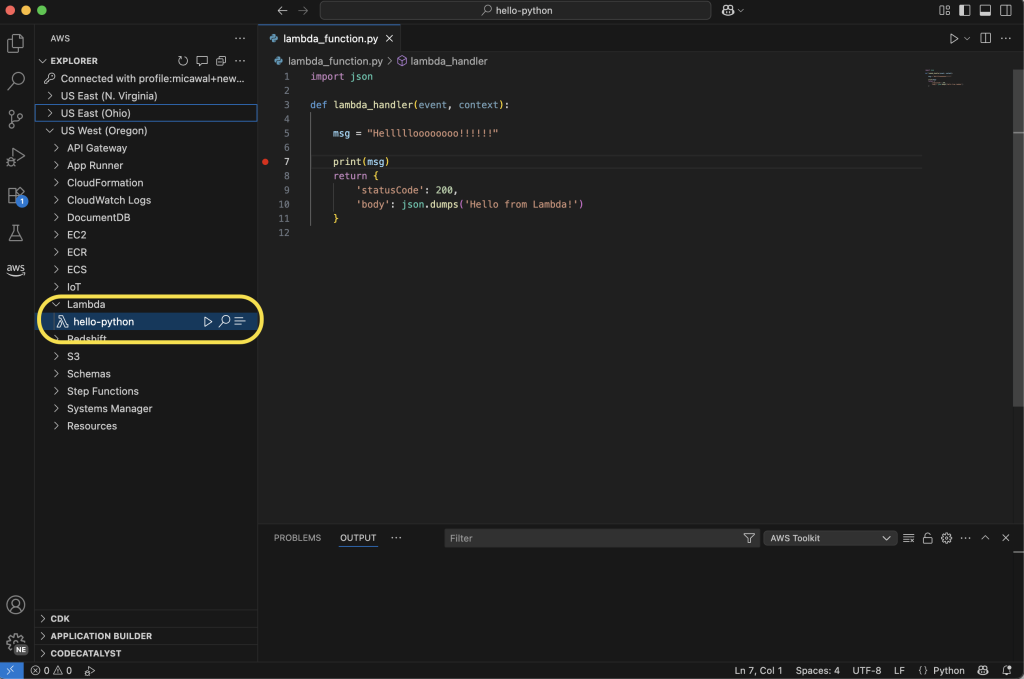
To take remote debugging for a spin, I chose to start with a basic “hello world” example function, written in Python. I had previously created the function using the AWS Management Console for AWS Lambda. Using the AWS Toolkit for VS Code, I can navigate to my function in the Explorer pane. Hovering over my function, I can right-click (ctrl-click in Windows) to download the code to my local machine to edit the code in my IDE. Saving the file will ask me to decide if I want to deploy the latest changes to Lambda.

Screenshot view of the Lambda Debugger in VS Code

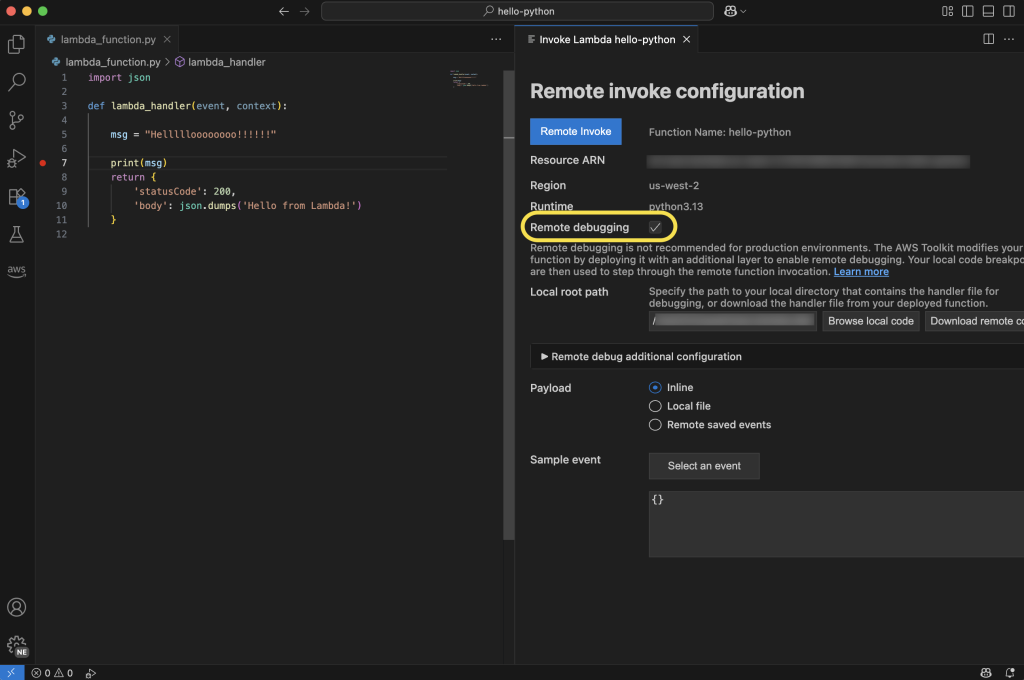
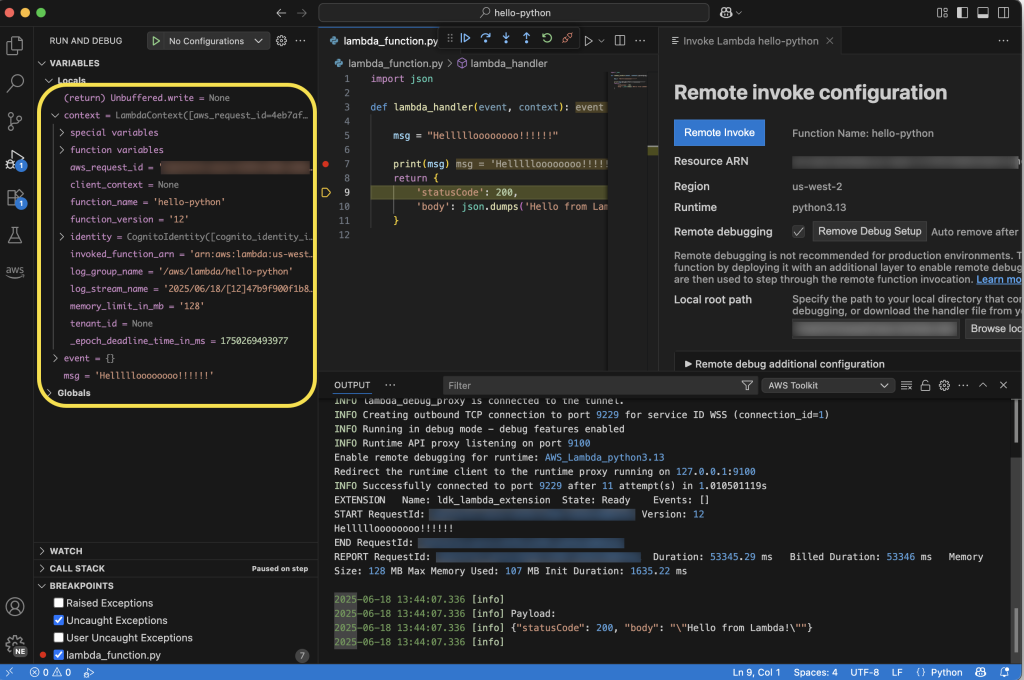
From here, I can select the play icon to open the Remote invoke configuration page for my function. This dialog will now display a Remote debugging option, which I configure to point at my local copy of my function handler code. Before choosing Remote invoke, I can set breakpoints on the left anywhere I want my code to pause for inspection.

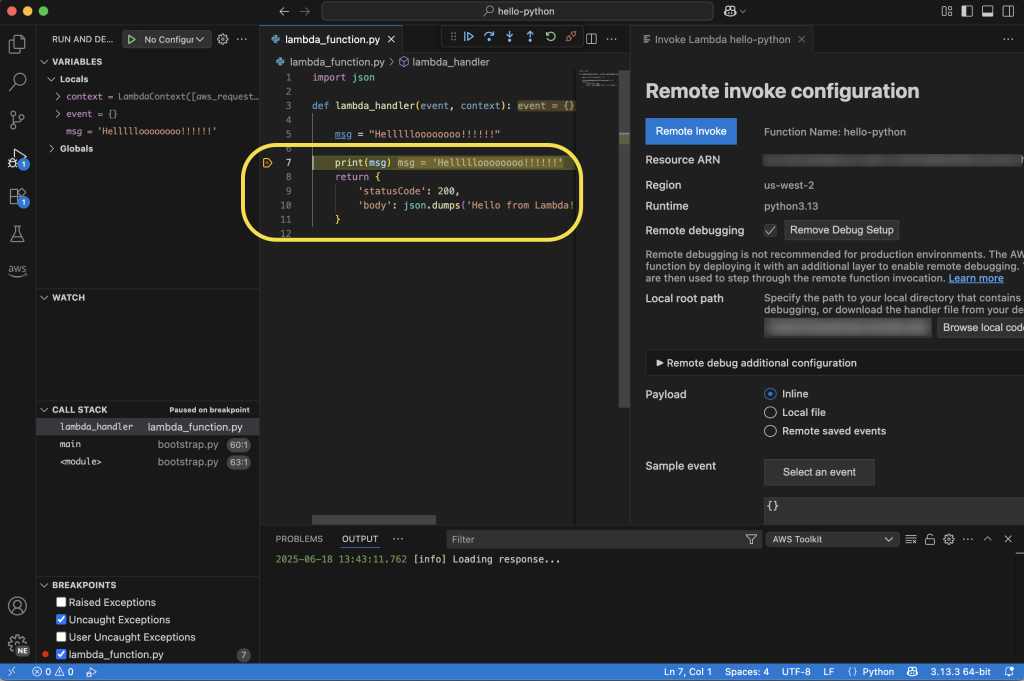
My code will be running in the cloud after it’s invoked, and I can monitor its status in real time in VS Code. In the following screenshot, you can see I’ve set a breakpoint at the print statement. My function will pause execution at this point in my code, and I can inspect things like local variable values before either continuing to the next breakpoint or stepping into the code line by line.

Here, you can see that I’ve chosen to step into the code, and as I go through it line by line, I can see the context and local and global variables displayed on the left side of the IDE. Additionally, I can follow the logs in the Output tab at the bottom of the IDE. As I step through, I’ll see any log messages or output messages from the execution of my function in real time.

Enhanced development workflow

These new capabilities work together to create a more streamlined development experience. Developers can start in the console, quickly transition to VS Code using the console to IDE integration, and then use remote debugging to debug their functions running in the cloud. This workflow eliminates the need to switch between multiple tools and environments, helping developers identify and fix issues faster.

Now available

You can start using these new features through the AWS Management Console and VS Code with the AWS Toolkit for VS Code (v3.69.0 or later) installed. Console to IDE integration is available in all commercial AWS Regions where Lambda is available, except AWS GovCloud (US) Regions. Learn more about it in Lambda and AWS Toolkit for VS Code documentation. To learn more about remote debugging capability, including AWS Regions it is available in, visit the AWS Toolkit for VS Code and Lambda documentation.

Console to IDE and remote debugging are available to you at no additional cost. With remote debugging, you pay only for the standard Lambda execution costs during debugging sessions. Remote debugging will support Python, Node.js, and Java runtimes at launch, with plans to expand support to additional runtimes in the future.

These enhancements represent a significant step forward in simplifying the serverless development experience, which means developers can build and debug Lambda functions more efficiently than ever before.

Modernizing SOAP applications using Amazon API Gateway and AWS Lambda

Post Syndicated from Daniel Abib original https://aws.amazon.com/blogs/compute/modernizing-soap-applications-using-amazon-api-gateway-and-aws-lambda/

This post demonstrates how you can modernize legacy SOAP applications using Amazon API Gateway and AWS Lambda to create bidirectional proxy architectures that enable integration between SOAP and REST systems without disrupting existing business operations.

Many organizations today face the challenge of maintaining critical business systems that were built decades ago. These legacy applications power essential business operations despite relying on outdated technologies and integration patterns. Although complete system replacement would be ideal, practical constraints such as budget limitations, resource availability, technical complexity, and missing documentation often make modernization efforts challenging.

This post first shows proxy architecture patterns to expose a legacy SOAP server over a REST API. It then shows how to integrate a legacy SOAP client with applications using a REST API.

While SOAP and REST APIs share HTTP as their foundation, SOAP has some limitations compared to REST, like limited HTTP methods (GET/POST only) and mandatory XML formatting. REST is more flexible with multiple HTTP methods and diverse payload formats (plain text, binary, HTML, JSON, XML).

Using API Gateway and Lambda to proxy SOAP service

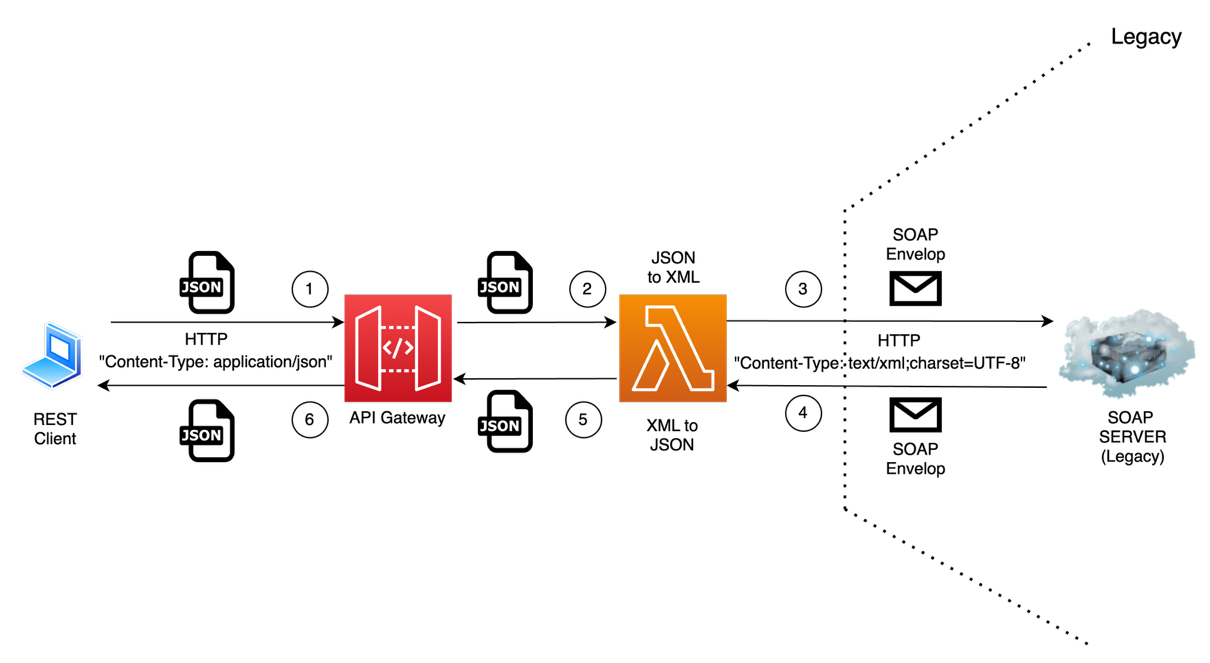
Consider a legacy solution that only supports SOAP. The following diagram shows the architecture for a SOAP proxy server using API Gateway and Lambda.

Figure 1: SOAP Server Proxy for modernized architecture

Figure 1: SOAP Server Proxy for modernized architecture

The proxy exposes the APIs hosted on the SOAP Server (on the right side of the image) over a REST interface. A SOAP service expects the HTTP Content-Type header set to text/xml, and a XML format payload that follows the WSDL specification defined by the server.

In the proposed architecture, the Lambda function is the core transformation engine, handling the bidirectional conversion between JSON and XML formats. Lambda functions can be developed in multiple programming languages such as Python, Node.js, Java, C#, Go, Ruby, and PowerShell, allowing you to use your existing development expertise. The serverless nature of Lambda provides automatic scaling to handle traffic spikes without needing infrastructure management or capacity planning.

API Gateway acts as the intelligent front door, managing all incoming requests and routing them appropriately. It provides enterprise-grade features such as request throttling to protect backend systems from overload, comprehensive authentication and authorization mechanisms, API key management for partner access control, request and response validation, caching capabilities for improved performance, and detailed monitoring and logging. These built-in features remove the need for custom middleware development and provide immediate operational benefits. API Gateway can receive multiple payload format such as XML, JSON, binary data, and plain text. This makes it suitable for diverse integration scenarios.

Using API Gateway and Lambda to support legacy SOAP clients

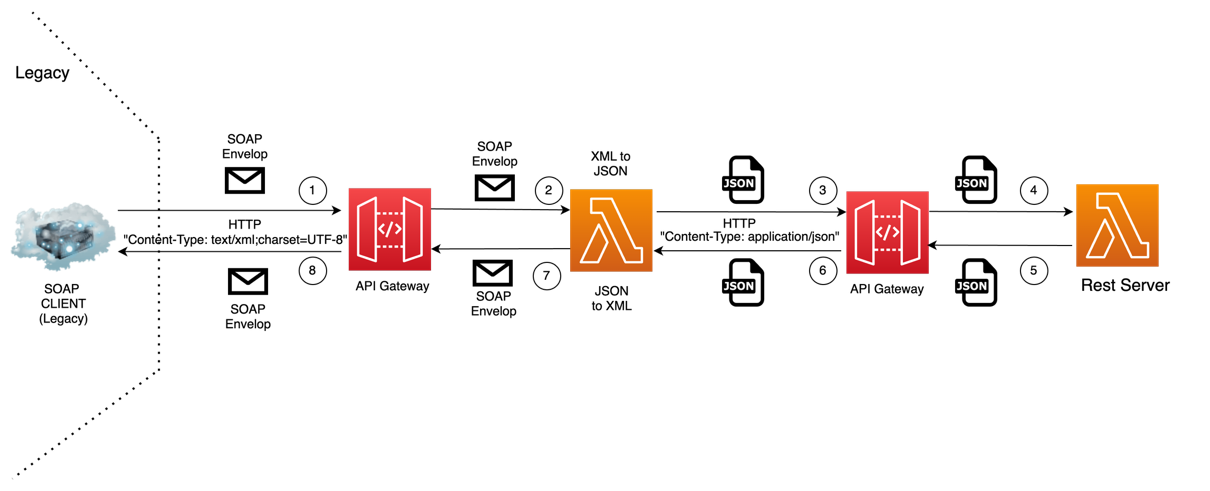
The previous section focused on exposing SOAP services over REST APIs. Organizations also face the reverse challenge where legacy SOAP client applications must access REST services. The architecture for supporting legacy SOAP clients follows a similar pattern but with reversed data flow. In this case, the legacy SOAP client sends XML-formatted requests to what it believes is a SOAP server. However, behind the scenes API Gateway and Lambda work together to translate these requests into REST API calls.

Figure 2: Legacy SOAP client modernization architecture

Figure 2: Legacy SOAP client modernization architecture

The legacy SOAP client application sends XML SOAP messages to API Gateway. The Lambda function receives these SOAP requests, extracts the relevant data from the XML envelope, and transforms it into JSON format for the modern REST service.

The Lambda function wraps the JSON response from the REST services into the SOAP XML format that the legacy client expects. It recreates the appropriate XML structure, SOAP headers, and ensures that the response conforms to the WSDL specification that the client application was designed to consume.

Example scenario

Let’s suppose our legacy client application needs to send a SOAP request to convert an integer number to its word form. The SOAP envelop to convert the number 1519 to its long form “one thousand, five hundred and nine” looks like this:

<?xml version="1.0" encoding="utf-8"?>
<soap:Envelope xmlns:soap="http://schemas.xmlsoap.org/soap/envelope/">
    <soap:Body> \
        <ConvertNumberToWordsSoapIn>
            <NumberToWordsRequest>1519</NumberToWordsRequest>
        </ConvertNumberToWordsSoapIn>
    </soap:Body>
</soap:Envelope>

The REST conversion service expects a JSON payload the as follownig:

jsonObject = {
	"data" : 1519
}

The following code block shows a sample Lambda function implementation for this. This function converts the SOAP XML envelop to JSON, changes the http header to application/json, and converts response from REST service to SOAP format.

var parseString = require('xml2js').parseString;
const axios = require('axios');

exports.handler = async (event, context) => {
    var valueNumber;
    
    try {
        console.log("Parsing XML string");

        // Parsing the XML to obtain data needed for conversion (number to words)
        parseString(event.body, function (err, result) {
            if (!err) {
                valueNumber = result['soap:Envelope']['soap:Body'][0]
                              ['ConvertNumberToWordsSoapIn'][0]
                              ['NumberToWordsRequest'][0];
            } else { 
                console.log (err);
                throw (err);
            }
        });
        console.log("Creating JSON for calling the service");
        // Creating JSON to call service
        var jsonObject = {
            "data" : valueNumber
        }
        
        console.log("Calling Microservice (NumberToWords)");
        const headers = { 
            'Content-Type': 'Application/json'
        };
        
        console.log ("Parameter for NumberToWords URL:" + 
                    JSON.stringify(process.env.NumberToWordMicroservice));

        // Calling numberToWords REST Server
        var resultNumberToWords = await 
            axios.post(process.env.NumberToWordMicroservice, jsonObject, { headers });
        
        // Creating the response
        console.log("Creating response XML");

        var resp =  create_response (JSON.stringify(resultNumberToWords.data.message));
        console.log("Response in XML: "+ resp);
        
        // Returning the value in XML using text/xml content type
        let response = {'statusCode': 200, headers: {"content-type": "text/xml"}, 
                        'body': JSON.stringify(resp)}
        return response;
        
    } catch (err) {
        console.log ("Error: " + err);
        let response = {'statusCode': 500, 
                        headers: {"content-type": "text/xml"}, 'body': err}
        return response;
    }
};

// Function to create a SOAP XML envelope with the result value
function create_response(numberInWords) {
  return '<?xml version="1.0" encoding="utf-8"?> \
            <soap:Envelope xmlns:soap="http://schemas.xmlsoap.org/soap/envelope/">\
            <soap:Body>\
              <m:ConvertNumberToWordsResponse xmlns:m="http://www.dataaccess.com/webservicesserver/"> \
                  <m:ConvertNumberToWordsResponseResult>' + numberInWords + '</m:ConvertNumberToWordsResponseResult> \
              </m:ConvertNumberToWordsResponse> \
            </soap:Body>\
            </soap:Envelope>';
}

With this approach, you can maintain your existing SOAP client applications without modification, allowing them to consume modern REST services. You can preserve investments in legacy client applications while gradually modernizing the overall system. This architecture is particularly valuable in scenarios where multiple legacy SOAP clients need to access the same modern REST services. This is because a single proxy can serve multiple client applications simultaneously. The serverless nature of the architecture makes sure that it scales automatically based on the number of client requests, providing cost-effective operation regardless of usage patterns.

Alternative approach using API Gateway transformation capabilities

The Lambda-based approach provides maximum flexibility and control. API Gateway also offers built-in transformation capabilities that can handle certain SOAP modernization scenarios without the need for compute resources.

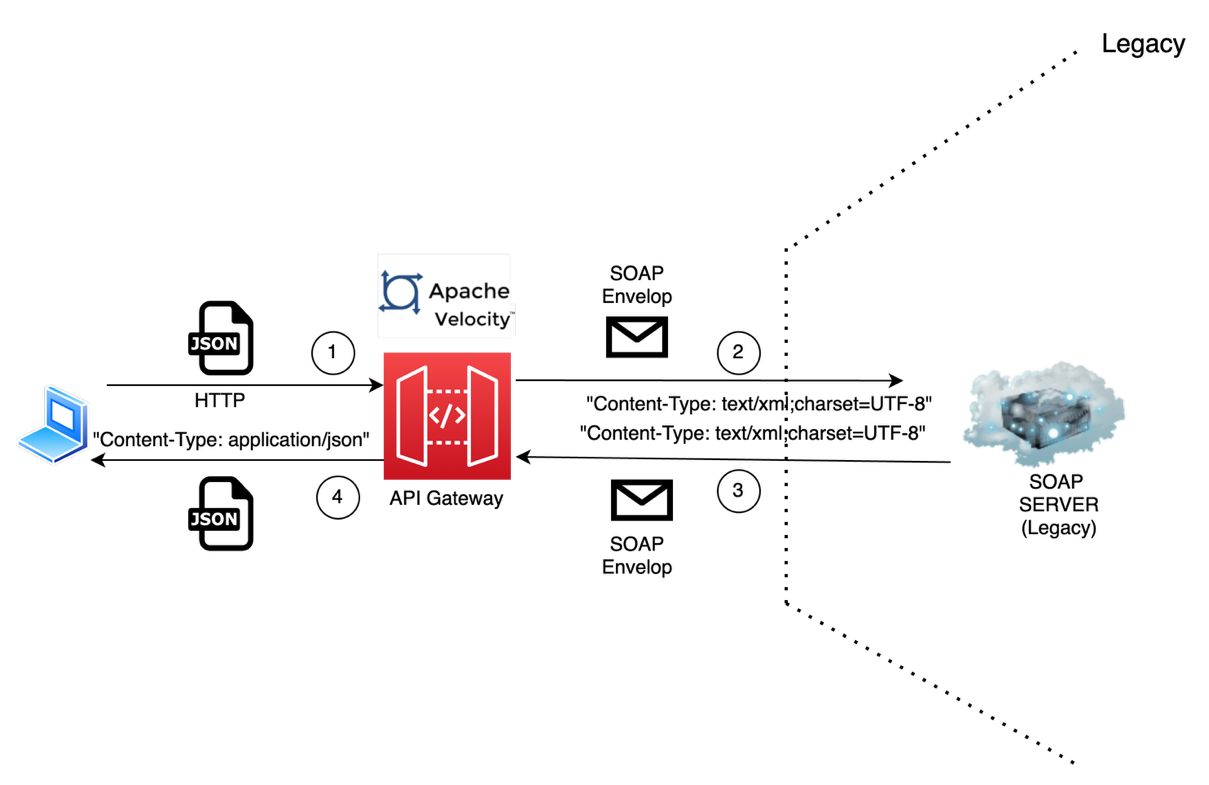
The native API Gateway transformation uses Apache Velocity Template Language mapping templates. It converts the payload directly at the gateway, offering a streamlined solution for specific modernization scenarios.

The VTL approach works by defining mapping templates that handle the conversion process between different payload formats. When modernizing SOAP services, these templates can intercept REST requests with JSON payloads, restructure the data into XML format compatible with your legacy SOAP endpoints, and reverse the process for responses returning to the client.

Figure 3: API Gateway with velocity template language transformation

Figure 3: API Gateway with velocity template language transformation

This gateway-native transformation strategy offers several operational advantages. You benefit from streamlined architecture because the transformation logic resides entirely within the API Gateway service. There are no other infrastructure components to manage or monitor, and the solution avoids the complexity of coordinating between multiple AWS services. Cost efficiency is another key benefit, as there are no compute charges beyond the standard API Gateway pricing.

Consider the previous example of converting a number to its word format. The VTL transformation in API Gateway will look like this:

## Parse the SOAP envelope and extract the number value
#set(\$xmlDoc = \$input.path('\$'))
#set(\$numberToWords = \$xmlDoc.Envelope.Body.ConvertNumberToWordsSoapIn.NumberToWordsRequest)

## Convert to integer if it's a string
#if(\$numberToWords.toString().matches("^\d+\$"))
  #set(\$dataValue = \$numberToWords.toInteger())
#else
  #set(\$dataValue = \$numberToWords)
#end

{
  "data": \$dataValue
}

You should consider VTL transformations when your SOAP services have predictable, stable schemas with relatively direct XML structures. This approach works particularly well for legacy systems that rarely undergo changes and have clear request-response patterns. For more dynamic environments or complex transformation requirements, the Lambda-based solution provides superior flexibility and maintainability.

Security considerations

An important consideration when working with legacy SOAP services is understanding their authentication mechanisms. SOAP protocols often implement authentication through security standards, where authentication credentials and security tokens are embedded directly within the SOAP envelope headers. This includes username tokens, digital signatures, and encryption elements that are part of the XML structure.

When SOAP envelopes contain unencrypted authentication information in the headers, the proxy architecture typically functions without more modifications. This is because the Lambda function can pass through these authentication elements transparently to the backend SOAP service. However, due to the nature of SOAP authentication being tightly integrated with the XML envelope structure, certain scenarios may need custom handling within the Lambda function.

For example, if the SOAP service uses timestamp-based authentication tokens, session management, or needs specific security header modifications, the Lambda function may need customization to properly handle, validate, or refresh these authentication elements during the JSON-to-XML transformation process. Organizations should carefully analyze their SOAP service authentication requirements to determine if more Lambda logic is needed to maintain security compliance.

Moreover, make sure that any SOAP authentication credentials processed by the Lambda function are handled securely and never logged in plain text.

Conclusion

In this post, you learned how cloud-native services can bridge the gap between legacy systems and modern application architectures, allowing you to use your existing investments while adopting contemporary development practices and technologies.

Amazon API Gateway and AWS Lambda enable organizations to create REST services that proxy legacy SOAP servers, allowing modern applications to consume legacy services through JSON payloads while preserving existing SOAP infrastructure. This serverless solution provides cost-effectiveness, automatic scaling, and reduced operational overhead while facilitating company modernization through scalable APIs without abandoning legacy software investments.

This modernization strategy allows you to gradually transition from legacy SOAP services to modern REST APIs without disrupting existing business operations. As your modernization journey progresses, you can extend this pattern to support more SOAP services or implement more sophisticated transformation logic based on your specific business requirements.

For more serverless learning resources, visit Serverless Land.

Orchestrating document processing with AWS AppSync Events and Amazon Bedrock

Post Syndicated from Mehdi Amrane original https://aws.amazon.com/blogs/compute/orchestrating-document-processing-with-aws-appsync-events-and-amazon-bedrock/

Many organizations implement intelligent document processing pipelines in order to extract meaningful insights from an increasing volume of unstructured content (such as insurance claims, loan applications and more). Traditionally, these pipelines require significant engineering efforts, as the implementation often involves using several machine learning (ML) models and orchestrating complex workflows.

As organizations integrate these pipelines to customer facing applications (such as web applications for customers to upload documents such as insurance claims, loan approval documents and more), they set goals to provide insights in real time to increase the end customer experience. These organizations also aim to run and scale these workloads with minimal operational overhead and optimizing on costs. In addition, these organizations require the implementation of common security practices such as identity and access management, to make sure that only authorized and authenticated users are allowed to perform specific actions or access specific resources.

In this post, we show you a solution to simplify the creation of an intelligent document processing pipeline, with a web application for customers to upload their files (documents and images) and derive insights from it (summarization, fields extraction and classification). The solution primarily use serverless technologies, it includes a web socket to receive insights in real time and offers several benefits, such as automatic scaling, built-in high availability, and a pay-per-use billing model to optimize on costs. The solution also includes an authentication layer and an authorization layer to manage identities and permissions.

Solution overview

In this post, we provide an operational overview of the solution, and then describe how to set it up with the following services:

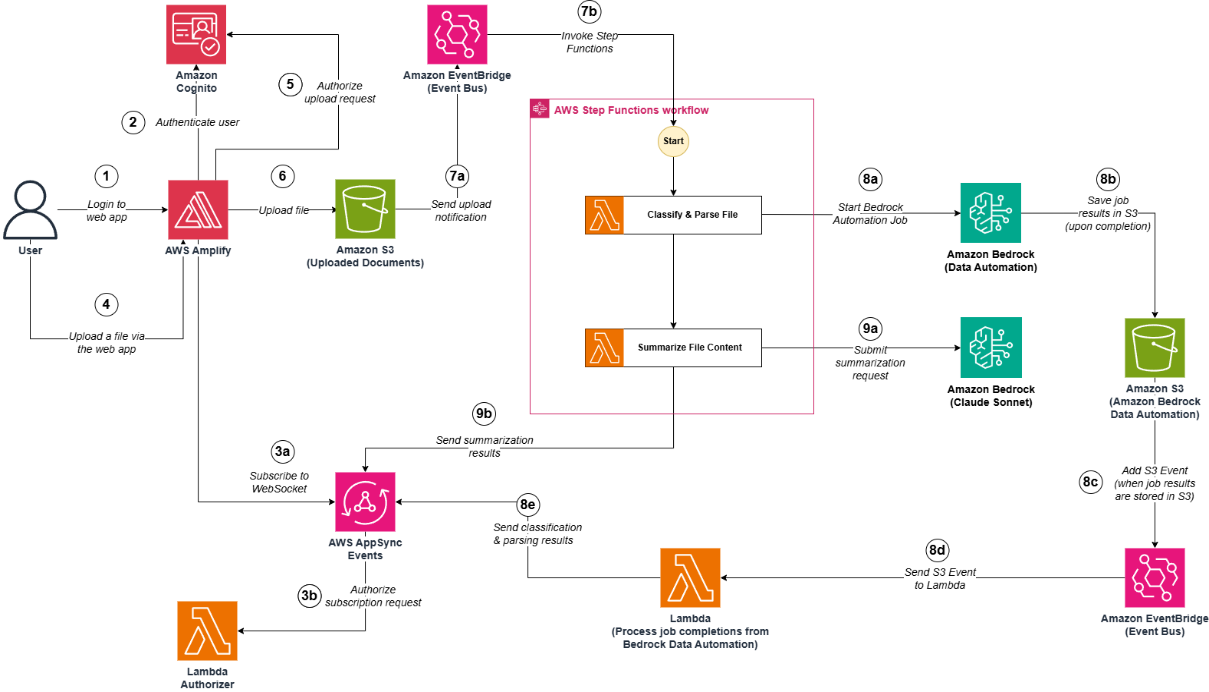
The solution architecture is illustrated in the following diagram:

Step 1: The user authenticates to the web application (hosted in AWS Amplify).
Step 2: Amazon Cognito validates the authentication details. After this, the user is now logged in the web application.
Steps 3aand 3b:

  • Step 3a: The web application (AWS Amplify) subscribes to an AWS AppSync Events web socket.
  • Step 3b: The AWS AppSync Events web socket calls an AWS Lambda authorizer to confirm that the user is authorized to subscribe to the web socket.

Step 4: The user uploads a file (document or image) using the web application.
Step 5: The web application (hosted in AWS Amplify) calls Amazon Cognito (identity pool) to confirm that the user is authorized to upload a file.
Step 6: The file is uploaded in an Amazon S3 bucket.
Steps 7a and 7b: Upon reception of an Amazon S3 upload event (which notifies that the file was uploaded in the Amazon S3 bucket) in the default Amazon Event Bridge bus, an Amazon Event Bridge bus rule triggers the execution of an AWS Step Functions state machine to start the orchestration workflow.
Step 8 (Step to extract fields from a file and classify it):

  • Step 8a: The first AWS Lambda function starts a new Amazon Bedrock Automation job (this job extracts specific fields from the uploaded file and classify it)
  • Step 8b: Once the job is completed, the results are stored in an Amazon S3 bucket.
  • Step 8c and 8d: Upon reception of an Amazon S3 event (which notifies that the results were stored in the Amazon S3 bucket) in the default Amazon Event Bridge, an Amazon Event Bridge bus rule triggers the execution of an AWS Lambda function
  • Step 8e: An AWS Lambda function publishes the results to the web socket.

Steps 9a and 9b: The second AWS Lambda function submits a prompt to an Amazon Bedrock foundation model (Sonnet 3), to request a summarization in streaming of the uploaded file. The AWS Lambda function publishes the streaming data to the web socket.

After Step 8e and Step 9b, the user can now consult the summarization result and extraction insights of the uploaded file in the web application.

Pre-requisites

To follow along and set up this solution, you must have the following:

  • An AWS account
  • A device with access to your AWS account with the following:
    • Python 3.12 installed (including pip)
    • Node.js 20.12.0 installed
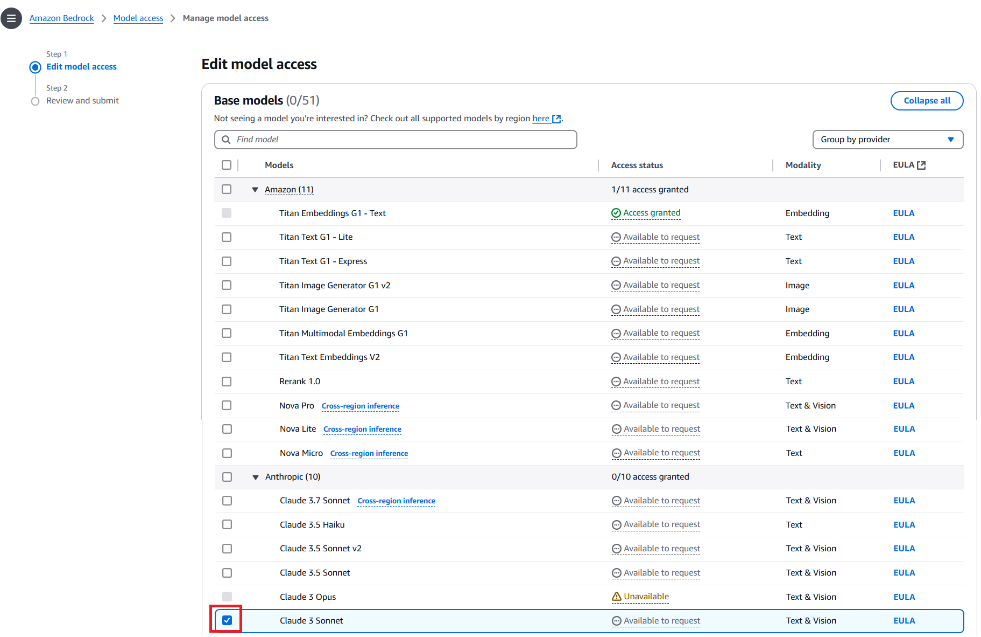
  • Enable Model Access to the Claude 3 Sonnet model in Amazon Bedrock


Note: Deploying this solution will incur costs. Review the pricing page of each AWS service used in this post for details on costs. The cost of running this solution will primarily depend on:

  • The number of documents (and the size of each document)
  • The number of active users

Setup Amazon Bedrock Data Automation

In this section, we setup an Amazon Bedrock Data Automation project and an Amazon Bedrock blueprint.

A project contains a list of blueprints, and each blueprint defines the fields to extract from different types of files (such as documents or images). In this post, we define a blueprint for a driving license.

Complete the following steps to create an Amazon Bedrock Data Automation project and a driving license blueprint:

  1. Clone the GitHub repository
    git clone https://github.com/aws-samples/sample-create-idp-with-appsyncevents-and-amazonbedrock.git

  2. Go to the sample-create-idp-with-appsyncevents-and-amazonbedrock folder
    cd sample-create-idp-with-appsyncevents-and-amazonbedrock

  3. Initialize the environment (make the shell script files, from the GitHub repository, ready to be used)
    chmod +x ./init-env.sh && source ./init-env.sh

  4. Run the script setup-bda-project.sh to create an Amazon Bedrock Data Automation project and a sample driving license blueprint:
    ./setup-bda-project.sh

Create the web socket and orchestration backend

In this section, we create the following resources:

  • A user directory for web authentication and authorization, created with an Amazon Cognito user pool. An Amazon Cognito identity pool is also created to validate that users are authorized to upload files via the web application.
  • A web socket using AWS AppSync Events. This allows our web application to receive real time updates for summarization and extraction results. An authorization layer is also created to protect the web socket from unauthorized users. This is implemented with a Lambda authorizer function to validate that incoming requests include valid authorization details.
  • A state machine using AWS Step Functions and AWS Lambda to orchestrate the summarization and extraction operations from the unstructured content
  • Amazon S3 buckets to store files for document processing, and code files for AWS Lambda functions

Complete the following steps to create the web socket and the orchestration backend of the solution, using AWS CloudFormation templates:

  1. Create Amazon S3 buckets used by the solution by running the following script. These buckets will store the files uploaded by users and code files of the AWS Lambda functions used in this solution.
    cd $CURRENT_DIR/s3; ./create-s3-buckets.sh

  2. Create the Amazon Cognito user pool and identity pool by running the create-cognito-userpool.sh script:
    cd $CURRENT_DIR/cognito; ./create-cognito-userpool.sh

  3. Create the AWS AppSync Events web socket by running the following script:
    cd $CURRENT_DIR/appsync/; ./create-appsync-api.sh

  4. Create the AWS Step Functions state machine (including AWS Lambda functions) by running the following scripts:
    cd $CURRENT_DIR/orchestration/; ./create-orchestration.sh

Configure the Amazon Cognito user pool

In this section, we create a user in our Amazon Cognito user pool. This user will log in to our web application.

Run the script create-cognito-testuser.sh to create the user (make sure to provide your email address):

cd $CURRENT_DIR/cognito; ./create-cognito-testuser.sh #your-email-address#

After you create the user, you should receive an email with a temporary password in this format: “Your username is #your-email-address# and temporary password is #temporary-password#.”

Keep note of these login details (email address and temporary password) to use later when testing the web application.

Create the web application

In this section, we build a web application using AWS Amplify and publish it to make it accessible through an endpoint URL.

Complete the following steps to create the web application:

  1. Run the script create-webapp.sh to create the web application with AWS Amplify:
    cd $CURRENT_DIR/amplify/; ./create-webapp.sh

  2. Run the script deploy.sh to deploy the web application
    cd $CURRENT_DIR/amplify/amplify-idp; ./deploy.sh

The web application is now available for testing and a URL should be displayed, as shown in the following screenshot. Take note of the URL to use in the following section.

Test the web application

In this section, we test the web application and upload a file to be processed:

  1. Open the URL of the AWS Amplify application in your web browser.
  2. Enter your login information (your email and the temporary password you received earlier while configuring the user pool in Amazon Cognito) and choose Sign in.
  3. When prompted, enter a new password and choose Change Password.
  4. You should now be able to see a web interface.
  5. Download the sample driving license at this location and upload it via the web application using either your camera or a file in your local device, as illustrated

Once the file is uploaded, you should start receiving responses in the web application. When all the operations are completed, you should see a result equivalent to what is shown in the following screenshot:

Note: If you are planning to use other driving license sample images with other formats, you may have to update the existing Bedrock Data Automation blueprint we created earlier or define a new blueprint in your Bedrock Data Automation project we created earlier for these new images to work. For more information, please review the Bedrock Data Automation documentation.

Clean up

To make sure that no additional cost is incurred, remove the resources provisioned in your account. Make sure you’re in the correct AWS account before deleting the following resources.

Important note: You should exercise caution when performing the preceding steps. Make sure you are deleting the resources in the correct AWS account.

You can either navigate to the AWS CloudFormation console to delete the CloudFormation stacks associated to the resources provisioned or use the cleanup helper script cleanup.sh available at the root of the sample-create-idp-with-appsyncevents-and-amazonbedrock folder:

./cleanup.sh #region#

Conclusion

In this post, we walked through a solution to create a document processing pipeline, with a web application using serverless services. Via the web application, we were able to upload a file and receive responses in real time for different types of operations (summarization, extraction of specific fields and classification). First, we created an Amazon Bedrock Data Automation project (with a driving license blueprint). Then we created a web socket along with an orchestration solution using a state machine (AWS Step Functions and AWS Lambda functions). We also configured a user pool to grant a user access to the web application. Finally, we created the frontend of the web application in AWS Amplify.

To dive deeper into this solution, a self-paced workshop is available in AWS Workshop Studio.

Building serverless event streaming applications with Amazon MSK and AWS Lambda

Post Syndicated from Tarun Rai Madan original https://aws.amazon.com/blogs/big-data/building-serverless-event-streaming-applications-with-amazon-msk-and-aws-lambda/

As organizations build modern applications with event-driven architectures (EDA), they often seek solutions that minimize infrastructure management overhead while maximizing developer productivity. Amazon Managed Streaming for Apache Kafka (Amazon MSK) and AWS Lambda together provide a serverless, scalable, and cost-efficient platform for real-time event-driven processing.

In this post, we describe how you can simplify your event-driven application architecture using AWS Lambda with Amazon MSK. We demonstrate how to configure Lambda as a consumer for Kafka topics, including a cross-account setup and how to optimize price and performance for these applications.

Why use Lambda with Amazon MSK?

Customers building event-driven applications have several key priorities when it comes to their architecture choices. They typically seek to reduce their operational overhead by using Amazon Web Services (AWS) to handle the complex, underlying infrastructure components so their teams can focus on core business logic. Additionally, developers prefer a streamlined experience that minimizes the need for repetitive boilerplate code, enabling them to be more productive and focus on creating value. Furthermore, these customers want to achieve both scalability and cost-effectiveness without the burden of managing compute infrastructure directly. Lambda integration with Amazon MSK effectively addresses these requirements, delivering a comprehensive solution that combines the benefits of serverless computing with managed Kafka services. For example, an ecommerce company can use Amazon MSK to collect real-time clickstream data from its website and process those events using AWS Lambda. With this integration, they can trigger Lambda functions to update recommendation models, send personalized offers, or analyze user behavior instantly—without provisioning or managing servers. The key benefits of using Lambda with Amazon MSK include:

  1. Simplicity through native integration – AWS Lambda offers native integration with Amazon MSK through a connector resource called event source mapping. You can use this integration to directly associate a Kafka topic—whether it’s on Amazon MSK or a self-managed Kafka cluster—as an event source for a Lambda function without writing custom consumer logic. With just a few configuration steps, event source mapping handles partition assignment, offset tracking, and parallelized batch processing under the hood. It uses the Kafka consumer group protocol to distribute topic partitions across multiple concurrent Lambda invocations, supports batch windowing, and enables at-least-once delivery semantics. Moreover, it automatically commits offsets upon successful function execution while handling retries and dead-letter queue (DLQ) routing for failed records, significantly reducing the operational overhead traditionally associated with Kafka consumers.
  2. Auto scaling and throughput controls – When using AWS Lambda with Amazon MSK through event source mapping, Lambda automatically scales by assigning a dedicated event poller per Kafka partition, enabling parallel, partition-based processing. This allows the system to elastically handle varying traffic without manual intervention. For advanced control, provisioned concurrency pre-initializes Lambda execution environments, eliminating cold starts and delivering consistent low-latency performance. Additionally, with provisioned event source mapping, you can configure the minimum and maximum number of Kafka pollers, providing precise control over throughput and concurrency. This is ideal for applications with unpredictable traffic patterns or strict latency requirements.
  3. Cost-effectiveness – AWS Lambda uses a pay-per-use model in which you only pay for compute time and number of invocations. When integrated with Amazon MSK, there are no charges for idle time, making it ideal for bursty or low-frequency Kafka workloads. You can further optimize costs by tuning batch size and batch window settings. For mission-critical workloads, provisioned concurrency provides consistent performance with controlled pricing.
  4. Event filtering – AWS Lambda supports event filtering for Amazon MSK event sources, which means you can process only the Kafka records that match specific criteria. This reduces unnecessary function invocations and optimizes your function costs. You can define up to five filters per event source mapping (with the option to request an increase to ten). Each filter uses a JSON-based pattern to specify the conditions a record must meet to be processed. Filters can be applied using the AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS Serverless Application Model (AWS SAM) templates. For more details and examples, refer to the AWS Lambda documentation on event filtering with Amazon MSK.
  5. Handling Availability Zone outage for your consumer – Amazon MSK enables high availability for your Kafka brokers by distributing them across multiple Availability Zones within a Region. To maintain high availability across your application, you similarly need a consumer that offers high availability. AWS Lambda offers high availability and resilience by running your consumer functions across multiple Availability Zones in a Region. This means that even if one Availability Zone experiences an outage, your Lambda function will continue to operate in other healthy Availability Zones. While Lambda manages security patching and Availability Zone failure scenarios, you can focus on your application logic.
  6. Cross-account event processing – Cross-account connectivity between AWS Lambda and Amazon MSK allows a Lambda function in one AWS account to consume data from an MSK cluster in another account using MSK multi-VPC private connectivity powered by AWS PrivateLink. This setup is particularly beneficial for organizations that centralize Kafka infrastructure while maintaining separate accounts for different applications or teams.
  7. Support for JSON, Avro, Protobuf, and Schema Registries – AWS Lambda supports Kafka events in JSON, Avro and Protobuf formats via event source mapping. It integrates with AWS Glue Schema registry, Confluent Cloud Schema registry, and self-managed Confluent Schema registry , enabling native schema validation, filtering, and deserialization without custom code.

How Lambda processes messages from your Kafka topic

Lambda uses event source mappings to process records from Amazon MSK by actively polling Kafka topics through event pollers that invoke Lambda functions with batches of records. These mappings are Lambda managed resources designed for high-throughput, stream-based processing. By default, Lambda detects the OffsetLag for all partitions in your Kafka topic and automatically scales pollers based on traffic. For high-throughput applications, you can enable provisioned mode to define minimum and maximum pollers, and your event source mapping auto scales between the minimum and maximum defined values. In the provisioned mode, each poller can process up to 5 MBps and supports concurrent Lambda invocations.

After Lambda processes each batch, it commits the offsets of the messages in that batch. If your function returns an error for a message in a batch, Lambda retries the whole batch of messages until processing succeeds or the messages expire. You can send records that fail all retry attempts to an on-failure destination for later processing. To maintain ordered processing within a partition, Lambda limits the maximum event pollers to the number of partitions in the topic. When setting up Kafka as a Lambda event source, you can specify a consumer group ID to let Lambda join an existing Kafka consumer group. If other consumers are active in that group, Lambda will receive only part of the topic’s messages. If the group exists, Lambda starts from the group’s committed offset, ignoring the StartingPosition. The following diagram illustrates this flow.

Walkthrough: Build a serverless Kafka app with AWS Lambda

Follow these steps to build a serverless application that consumes messages from an MSK cluster using AWS Lambda:

  1. Create an Amazon MSK cluster. Use the AWS Management Console or AWS CLI to create your MSK cluster. When the cluster is up, create your Kafka topic(s). For detailed instructions, refer to the Amazon MSK documentation.
  2. Create a Lambda function using the AWS Management Console or the AWS CLI. To learn more about creating a Lambda function, refer to Create your first Lambda function. The Lambda function’s execution role needs to have the following permissions:
    1. Access to connect to your MSK cluster
    2. Permissions to manage elastic network interfaces in your VPC
  3. To connect Lambda to Amazon MSK as a consumer, set up event source mapping to link your MSK topic with the Lambda function. This allows Lambda to automatically poll for new messages and process them. Follow the guide on how to configure event source mapping.

For reference, configuring event source mapping involves three steps:

  1. Network setup – In the default event source mapping mode, you need to configure a networking setup using a PrivateLink endpoint or NAT gateway for event source mapping to invoke Lambda functions. In provisioned mode, no networking configuration is needed (and you don’t incur the cost of networking components).
  2. Event source mapping parameter configuration – This involves setting necessary configuration parameters for the event source mapping to be able to poll messages from your Kafka cluster. This includes the MSK cluster, topic name, consumer group ID, authentication method, and optionally, schema registry, scaling mode. You can configure the scaling mode for provisioned throughput, along with batch size, batch window, and event filtering for your event source mapping.
  3. Access permissions – This involves configuring required permissions to access the required AWS resources, and includes configuring permissions for the function to execute the code, permissions for the event source mapping to access your MSK cluster, and permissions for Lambda to access your VPC resources.

The following screenshot shows the console setup for configuring Amazon MSK event source mapping, including the Amazon MSK trigger related fields.

The following screenshot shows event poller configuration.

The following screenshot shows additional settings you can use, depending on your use case.

Optimizing AWS Lambda for stream processing with Amazon MSK

When building real-time data processing pipelines with Amazon MSK and AWS Lambda, it’s important to tune your setup for both performance and cost-efficiency. Lambda offers powerful serverless compute capabilities, but to get the most out of it in a streaming context, you need to make a few key optimizations:

  1. Enable provisioned concurrency for low-latency processing – For workloads that are sensitive to latency—cold starts can introduce unwanted delays. By enabling provisioned concurrency, you can pre-warm a specified number of Lambda instances so they’re always ready to handle traffic immediately. This eliminates cold starts and provides consistent response times, which is crucial for latency-critical use cases.
  2. Enable provisioned mode for event source mapping for high-throughput processing – For Kafka workloads with stringent throughput requirements, activate the provisioned mode. The optimal configuration of minimum and maximum event pollers for your Kafka event source mapping depends on your application’s performance requirements. Start with the default minimum event pollers to baseline the performance profile and adjust event pollers based on observed message processing patterns and your application’s performance requirements. For workloads with spiky traffic and strict performance needs, increase the minimum event pollers to handle sudden surges. You can fine-tune the minimum event pollers by evaluating your desired throughput, your observed throughput, which depends on factors such as the ingested messages per second and average payload size, and using the throughput capacity of one event poller (up to 5 MB/s) as reference. To maintain ordered processing within a partition, Lambda caps the maximum event pollers at the number of partitions in the topic.
  3. Optimize message batching using size and windowing – By integrating Lambda with Amazon MSK, you can control how messages are batched before they’re sent to your function. Tuning parameters such as batch size (the number of records per invocation: 1–10,000 records) and maximum batching window (how long to wait for a full batch: 0–300 seconds) can significantly impact performance. Larger batches mean fewer invocations, which reduces overhead and improves throughput. However, it’s important to strike a balance—too large a batch or window might introduce unwanted processing delays. Monitor your stream’s behavior and adjust these settings based on throughput requirements and acceptable latency.
  4. Apply filters to reduce unnecessary invocations – Not every record in your Kafka topic might require processing. To avoid unnecessary Lambda invocations (and associated costs), apply filtering logic directly when configuring the event source mapping. With Lambda, you can define filtering (up to 10 filters) criteria so that only relevant records trigger your function. This helps reduce compute time, minimize noise, and optimize your budget, especially when dealing with high-throughput topics with mixed content. For Amazon MSK, Lambda commits offsets for matched and unmatched messages after successfully invoking the function.

Conclusion

By combining Amazon MSK with AWS Lambda, you can seamlessly build modern, serverless event-driven applications. This integration eliminates the need to manage consumer groups, compute infrastructure, or scaling logic so teams can focus on delivering business value faster.

Whether you’re integrating Kafka into microservices, transforming data pipelines, or building reactive applications, Lambda with Amazon MSK is a powerful and flexible serverless solution. For detailed documentation on how to configure Lambda with Amazon MSK, refer to the AWS Lambda Developer Guide. For more serverless learning resources, visit Serverless Land.


About the Authors

Tarun Rai Madan is a Principal Product Manager at Amazon Web Services (AWS). He specializes in serverless technologies and leads product strategy to help customers achieve accelerated business outcomes with event-driven applications, using services like AWS Lambda, AWS Step Functions, Apache Kafka, and Amazon SQS/SNS. Prior to AWS, he was an engineering leader in the semiconductor industry, and led development of high-performance processors for wireless, automotive, and data center applications.

Masudur Rahaman Sayem is a Streaming Data Architect at AWS with over 25 years of experience in the IT industry. He collaborates with AWS customers worldwide to architect and implement sophisticated data streaming solutions that address complex business challenges. As an expert in distributed computing, Sayem specializes in designing large-scale distributed systems architecture for maximum performance and scalability. He has a keen interest and passion for distributed architecture, which he applies to designing enterprise-grade solutions at internet scale.

Introducing AWS Lambda native support for Avro and Protobuf formatted Apache Kafka events

Post Syndicated from Julian Wood original https://aws.amazon.com/blogs/compute/introducing-aws-lambda-native-support-for-avro-and-protobuf-formatted-apache-kafka-events/

AWS Lambda now provides native support for Apache Avro and Protocol Buffers (Protobuf) formatted events with Apache Kafka event source mapping (ESM) when using Provisioned Mode. The support allows you to validate your schema with popular schema registries. This allows you to use and filter the more efficient binary event formats and share data using schema in a centralized and consistent way. This blog post shows how you can use Lambda to process Avro and Protobuf formatted events from Kafka topics using schema registry integration.

This new capability works with both Amazon Managed Streaming for Apache Kafka (Amazon MSK), Confluent Cloud and self-managed Kafka clusters. To get started, update your existing Kafka ESM to Provisioned Mode and add schema registry configuration, or create a new ESM in Provisioned Mode with schema registry integration enabled.

Avro and Protobuf

Many organizations use Avro and Protobuf formats with Apache Kafka because these binary serialization formats offer advantages over JSON. They provide 50-80% smaller message sizes, faster serialization and deserialization performance, robust schema evolution capabilities, and strong typing across multiple programming languages.Working with these formats in Lambda functions previously necessitated custom code. Developers needed to implement schema registry clients, handle authentication and caching, write format-specific deserialization logic, and manage schema evolution scenarios.

What’s new

Lambda’s Kafka Event Source Mapping (ESM) now provides built-in integration with AWS Glue Schema Registry, Confluent Cloud Schema Registry, and self-managed Confluent Schema Registry. When you configure schema registry settings for your Kafka ESM, the service automatically validates incoming JSON Schema, Avro, and Protobuf records against their registered schema. This moves complex schema registry integration logic from your application layer to the managed Lambda service.

You can build your function with Kafka’s open-source ConsumerRecords interface using Powertools for AWS Lambda to get your Avro or Protobuf generated business objects directly. Optionally you can specify to get your records in the JSON format, where your function receives clean, validated JSON data regardless of the original serialization format, removing the need for custom deserialization code in your Lambda functions. This also allows you to create Kafka consumers across multiple programming languages.

Powertools for AWS Lambda is a developer toolkit that provides specific support for Java, .NET, Python, and TypeScript, maintaining consistency with existing Kafka development patterns. You can directly access business objects without custom deserialization code.

You can also setup filtering rules to discard irrelevant, JSON, Avro or Protobuf formatted events before function invocations, which can improve processing performance and reduce costs.

How schema validation works

When you configure schema registry integration for your Kafka ESM, you specify the registry endpoint, authentication details, and which event fields (key, value, or both) to validate. The ESM polls your Kafka topics for records as usual but now performs additional processing before invoking your Lambda function.For each incoming event, the ESM extracts the schema ID embedded in the serialized data. It fetches the corresponding schema from your configured registry. This process happens transparently, with schema definitions cached for up to 24 hours to optimize performance. The ESM identifies the format of your events using schema metadata and validates the event structure. It keeps either the original binary data or deserializes it to JSON format based on your customer configuration and sends it to your function for processing.


Figure 1: Kafka processing flow diagram.

The ESM handles schema evolution automatically. When producers begin using new schema versions, the service detects the updated schema IDs and fetches the latest definitions from your registry. This makes sure that your functions always receive properly deserialized data without requiring code changes.

Event record format

As a part of the ESM schema registry configuration, you need to specify Event Record Format, which Lambda uses to deliver validated records to your function. The schema registry configuration supports SOURCE and JSON.

SOURCE preserves the original binary format of the data as a base64-encoded string with producer-appended schema-id removed. This allows direct conversion to Avro or Protobuf objects so that you can use Kafka’s ConsumerRecords interface for a Kafka-like experience. Use this format when working with strongly typed languages or when you need to maintain the full capabilities of Avro or Protobuf schemas. Then, you can use any Avro or Protobuf deserializer to convert raw bytes to your business object. Powertools provides native support for this deserialization.

With JSON, the ESM deserializes the data ready for direct use in languages with native JSON support. Use this when you don’t need to preserve the original binary format or work with generated classes. You can also use Powertools to convert the base64 to your business object. See the documentation for payload formats and deserialization behavior.

If you configure filtering rules, then they operate on the JSON-formatted events after deserialization. This upstream filtering prevents unnecessary Lambda invocations for events that don’t match your processing criteria, directly reducing your compute costs.

Configuration and setup

To use this feature, you must enable Provisioned Mode for your Kafka ESM, which provides the dedicated compute resources needed for schema registry integration.

You can configure the integration through the AWS Management Console, AWS Command Line Interface (AWS CLI), AWS Language SDKs, or infrastructure as code (IaC) tools such as the AWS Serverless Application Model (AWS SAM) or AWS Cloud Development Kit (AWS CDK).

Your schema registry configuration includes the registry endpoint URL, authentication method (AWS Identity and Access Management (IAM) for AWS Glue Schema Registry, or Basic Auth, SASL/SCRAM, or mTLS for Confluent registries), and validation settings. You specify which event attributes to validate and optionally define filtering rules using standard Lambda event filtering syntax.

For error handling, configure Lambda failure destinations where events that fail schema validation or deserialization are sent. This makes sure that problematic events don’t disappear silently but are routed to other services such as Amazon Simple Queue Service (Amazon SQS), Amazon Simple Notification Service (Amazon SNS), and Amazon S3 for debugging and analysis.

Seeing the new features in action

There are a number of Serverless Patterns that you can use to process Kafka streams using Lambda. This example uses the Java pattern.

Deploy a sample Amazon MSK cluster

To set up an Amazon MSK cluster, follow the instructions in the GitHub repo and create a new AWS CloudFormation stack using the MSKAndKafkaClientEC2.yaml template file. The stack creates the Amazon MSK cluster, along with a client Amazon EC2 instance, to manage the Kafka cluster. There are costs involved when running this infrastructure.

  1. Connect to the EC2 instance using EC2 Instance Connect.
  2. Check that the Kafka topic is created by checking the contents of the kafka_topic_creator_output.txt file.
    cat kafka_topic_creator_output.txt

  3. The file should contain the text: “Created topic MskIamJavaLambdaTopic.”

Deploy the Glue schema registry and consumer Lambda function

The EC2 instance contains the software needed to deploy the schema registry and Lambda function.

  1. Change directory to the pattern directory.
    cd serverless-patterns/msk-lambda-iam-java-sam
  2. Build the application using AWS SAM.
    sam build
  3. To deploy your application for the first time, run the following in the EC2 instance shell:
    sam deploy --capabilities CAPABILITY_IAM --no-confirm-changeset \
    	--no-disable-rollback --region $AWS_REGION --stack-name msk-lambda-schema-avro-java-sam --guided

  4. You can accept all the defaults by hitting Enter. You can browse to the AWS Glue schema registry console and view the ContactSchema definition:
    {
      "type": "record",
      "name": "Contact",
      "fields": [
        {"name": "firstname", "type": "string"},
        {"name": "lastname", "type": "string"},
        {"name": "company", "type": "string"},
        {"name": "street", "type": "string"},
        {"name": "city", "type": "string"},
        {"name": "county", "type": "string"},
        {"name": "state", "type": "string"},
        {"name": "zip", "type": "string"},
        {"name": "homePhone", "type": "string"},
        {"name": "cellPhone", "type": "string"},
        {"name": "email", "type": "string"},
        {"name": "website", "type": "string"}
      ]
    }
    

    The consumer Lambda function ESM is configured for Provisioned Mode.

  5. View the ESM configuration from the Lambda console for the Lambda function name prefixed with msk-lambda-schema-avro-ja-LambdaMSKConsumer.
  6. Choose the MSK Lambda trigger which opens the Triggers pane under Configuration.
    Figure 2: View Lambda ESM schema configuration
  7. The configuration specifies using the Event record format SOURCE so your function can use Kafka’s native open-source ConsumerRecords interface. Powertools then deserializes the payload.
  8. The schema validation attribute is VALUE.
  9. The ESM filter configuration only processes the records that match zip codes of 2000.
  10. In your function code, specify the open-source Kafka ConsumersRecords interface by including Powertools for Lambda as a dependency. ConsumerRecords provides metadata about Kafka records and allows you to get direct access to your Avro/Protobuf generated business objects without requiring any additional deserialization code.
package com.amazonaws.services.lambda.samples.events.msk;

import com.amazonaws.services.lambda.runtime.Context;
import com.amazonaws.services.lambda.runtime.RequestHandler;
import org.apache.kafka.clients.consumer.ConsumerRecord;
import org.apache.kafka.clients.consumer.ConsumerRecords;
import org.slf4j.Logger;
import org.slf4j.LoggerFactory;
import software.amazon.lambda.powertools.kafka.Deserialization;
import software.amazon.lambda.powertools.kafka.DeserializationType;
import software.amazon.lambda.powertools.logging.Logging;

public class AvroKafkaHandler implements RequestHandler<ConsumerRecords<String, Contact>, String> {
    private static final Logger LOGGER = LoggerFactory.getLogger(AvroKafkaHandler.class);

    @Override
    @Logging(logEvent = true)
    @Deserialization(type = DeserializationType.KAFKA_AVRO)
    public String handleRequest(ConsumerRecords<String, Contact> records, Context context) {
        LOGGER.info("=== AvroKafkaHandler called ===");
        LOGGER.info("Event object: {}", records);
        LOGGER.info("Number of records: {}", records.count());
        
        for (ConsumerRecord<String, Contact> record : records) {
            LOGGER.info("Processing record - Topic: {}, Partition: {}, Offset: {}", 
                       record.topic(), record.partition(), record.offset());
            LOGGER.info("Record key: {}", record.key());
            LOGGER.info("Record value: {}", record.value());
            
            if (record.value() != null) {
                Contact contact = record.value();
                LOGGER.info("Contact details - firstName: {}, zip: {}", 
                           contact.getFirstname(), contact.getZip());
            }
        }
        
        LOGGER.info("=== AvroKafkaHandler completed ===");
        return "OK";
    }
}
Produce and consumer records

To send messages to Kafka, there is a LambdaMSKProducerJava function.

  1. Invoke the function from the Lambda console or CLI within the EC2 instance.
    sam remote invoke LambdaMSKProducerJavaFunction --region $AWS_REGION \
    	--stack-name msk-lambda-schema-avro-java-sam

  2. You can view the Producer logs to see the 10 records produced.The consumer Lambda function processes the records.
  3. View the consumer Lambda function logs using the Amazon CloudWatch logs console or CLI within the EC2 instance.
    sam logs --name LambdaMSKConsumerJavaFunction \
    	--stack-name msk-lambda-schema-avro-java-sam --region $AWS_REGION

The Lambda function processes and logs only the records that match the filter FILTER. The Avro binary data is deserialized using Powertools for AWS Lambda. You should see the function logs showing each record processed with the decoded keys and values.


Figure 3: Lambda consumer logs showing Avro processing

Cleaning up

You can clean up the example Lambda function by running the sam delete command.

sam delete

If you created the Amazon MSK cluster and EC2 client instance, then navigate to the CloudFormation console, choose the stack, and choose Delete.

Performance and cost considerations

Schema validation and deserialization can add processing time before your function invocation. However, this overhead is typically minimal when compared to the benefits. ESM caching minimizes schema registry API calls. Using filtering allows you to reduce costs, depending on how effectively your filtering rules eliminate irrelevant events. This feature simplifies the operational overhead of managing schema registry integration code so teams can focus on business logic rather than infrastructure concerns.

Error handling and monitoring

If schema registries become temporarily unavailable, then cached schemas allow event processing to continue until the registry is available again. Authentication failures generate error messages with automatic retry logic. Schema evolution happens seamlessly as Lambda automatically detects and fetches new versions.

If events fail validation or deserialization, they are routed to your configured failure destinations. For Amazon SQS and Amazon SNS destinations, the service sends metadata about the failure. For Amazon S3 destinations, both metadata and the original serialized payload are included for detailed analysis.

You can use standard Lambda monitoring, with more CloudWatch metrics providing visibility into schema validation success rates, registry API usage, and filtering effectiveness.

Conclusion

AWS Lambda now supports Avro and Protobuf formats for Kafka event processing in Provisioned Mode for Kafka ESM. This enables schema validation, event filtering, and integration with both Amazon MSK, Confluent, and self-managed Kafka clusters. Whether you’re building new Kafka applications or migrating existing consumers to Lambda, this native schema registry integration streamlines processing pipelines.

For more information about the Lambda Kafka integration capabilities, go to the learning guide, Lambda ESM documentation. To learn about Lambda pricing, such as Provisioned Mode costs, visit the Lambda pricing page.

For more serverless learning resources, visit Serverless Land.

AWS Weekly Roundup: re:Inforce re:Cap, Valkey GLIDE 2.0, Avro and Protobuf or MCP Servers on Lambda, and more (June 23, 2025)

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-reinforce-recap-valkey-glide-2-0-avro-and-protobuf-or-mcp-servers-on-lambda-and-more-june-23-2025/

Last week’s hallmark event was the security-focused AWS re:Inforce conference.


AWS re:Inforce 2025

AWS re:Inforce 2025

Now a tradition, the blog team wrote a re:Cap post to summarize the announcements and link to some of the top blog posts.

To further summarize, several new security innovations were announced, including enhanced IAM Access Analyzer capabilities, MFA enforcement for root users, and threat intelligence integration with AWS Network Firewall. Other notable updates include exportable public SSL/TLS certificates from AWS Certificate Manager, a simplified AWS WAF console experience, and a new AWS Shield feature for proactive network security (in preview). Additionally, AWS Security Hub has been enhanced for risk prioritization (Preview), and Amazon GuardDuty now supports Amazon EKS clusters.

But my favorite announcement came from the Amazon Verified Permissions team. They released an open source package for Express.js, enabling developers to implement external fine-grained authorization for web application APIs. This simplifies authorization integration, reducing code complexity and improving application security.

The team also published a blog post that outlines how to create a Verified Permissions policy store, add Cedar and Verified Permissions authorisation middleware to your app, create and deploy a Cedar schema, and create and deploy Cedar policies. The Cedar schema is generated from an OpenAPI specification and formatted for use with the AWS Command Line Interface (CLI).

Let’s look at last week’s other new announcements.

Last week’s launches
Apart from re:Inforce, here are the launches that got my attention.

Kafka customers use Avro and Protobuf formats for efficient data storage, fast serialization and deserialization, schema evolution support, and interoperability between different programming languages. They utilize schema registries to manage, evolve, and validate schemas before data enters processing pipelines. Previously, you were required to write custom code within your Lambda function to validate, deserialize, and filter events when using these data formats. With this launch, Lambda natively supports Avro and Protobuf, as well as integration with GSR, CCSR, and SCSR. This enables you to process your Kafka events using these data formats without writing custom code. Additionally, you can optimize costs through event filtering to prevent unnecessary function invocations.

  • Amazon S3 Express One Zone now supports atomic renaming of objects with a single API call – The RenameObject API simplifies data management in S3 directory buckets by transforming a multi-step rename operation into a single API call. This means you can now rename objects in S3 Express One Zone by specifying an existing object’s name as the source and the new name as the destination within the same S3 directory bucket. With no data movement involved, this capability accelerates applications like log file management, media processing, and data analytics, while also lowering costs. For instance, renaming a 1-terabyte log file can now complete in milliseconds, instead of hours, significantly accelerating applications and reducing costs.
  • Valkey introduces GLIDE 2.0 with support for Go, OpenTelemetry, and pipeline batching – AWS, in partnership with Google and the Valkey community, announces the general availability of General Language Independent Driver for the Enterprise (GLIDE) 2.0. This is the latest release of one of AWS’s official open-source Valkey client libraries. Valkey, the most permissive open-source alternative to Redis, is stewarded by the Linux Foundation and will always remain open-source. Valkey GLIDE is a reliable, high-performance, multi-language client that supports all Valkey commands

GLIDE 2.0 introduces new capabilities that expand developer support, improve observability, and optimise performance for high-throughput workloads. Valkey GLIDE 2.0 extends its multi-language support to Go (contributed by Google), joining Java, Python, and Node.js to provide a consistent, fully compatible API experience across all four languages. More language support is on the way. With this release, Valkey GLIDE now supports OpenTelemetry, an open-source, vendor-neutral framework that enables developers to generate, collect, and export telemetry data and critical client-side performance insights. Additionally, GLIDE 2.0 introduces batching capabilities, reducing network overhead and latency for high-frequency use cases by allowing multiple commands to be grouped and executed as a single operation.

You can discover more about Valkey GLIDE in this recent episode of the AWS Developers Podcast: Inside Valkey GLIDE: building a next-gen Valkey client library with Rust.

Podcast episode on Valkey Glide

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Some other reading
My Belgian compatriot Alexis has written the first article of a two-part series explaining how to develop an MCP Tool server with a streamable HTTP transport and deploy it on Lambda and API Gateway. This is a must-read for anyone implementing MCP servers on AWS. I’m eagerly looking forward to the second part, where Alexis will discuss authentication and authorization for remote MCP servers.

Other AWS events
Check your calendar and sign up for upcoming AWS events.

AWS GenAI Lofts are collaborative spaces and immersive experiences that showcase AWS expertise in cloud computing and AI. They provide startups and developers with hands-on access to AI products and services, exclusive sessions with industry leaders, and valuable networking opportunities with investors and peers. Find a GenAI Loft location near you and don’t forget to register.

AWS Summits are free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Japan (this week June 25 – 26), Online in India (June 26), New-York City (July 16).

Save the date for these upcoming Summits in July and August: Taipei (July 29), Jakarta (August 7), Mexico (August 8), São Paulo (August 13), and Johannesburg (August 20) (and more to come in September and October).

Browse all upcoming AWS led in-person and virtual events here.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— seb

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

Networking of Amazon MQ for RabbitMQ event source mapping for AWS Lambda

Post Syndicated from Rafal Pawlaszek original https://aws.amazon.com/blogs/compute/networking-of-amazon-mq-for-rabbitmq-event-source-mapping-for-aws-lambda/

Event-driven architectures with message brokers need careful attention to security best practices. Amazon MQ for RabbitMQ combined with AWS Lambda enables serverless event processing. However, implementing defense in depth and least privilege principles necessitates a clear understanding of networking requirements. This is particularly important when working with different subnet types and their impact on service connectivity.

This post explores the networking aspects of Lambda event source mapping for Amazon MQ for RabbitMQ. Learn how deployment options influence your networking setup and security posture to make informed architectural decisions. These networking concepts are essential for building secure, scalable solutions, regardless of your experience level with message brokers.

For clarity in this post, when we refer to “RabbitMQ”, we mean Amazon MQ for RabbitMQ.

Prerequisites

The following prerequisites are necessary to complete this post:

  • An Amazon Web Services (AWS) account
  • Basic understanding of AWS networking concepts
  • Familiarity with Amazon MQ for RabbitMQ
  • Basic knowledge of Lambda

Furthermore, to enable setup of the discussed architectures, this post is accompanied by a GitHub repository that uses AWS Cloud Development Kit (AWS CDK).

Repository prerequisites

The following prerequisites are necessary for the repository:

Repository setup

Clone the https://github.com/aws-samples/sample-amazonmq-rabbitmq-lambda-esm repository. This repository contains all the necessary code and instructions to create relevant architectures using AWS CDK.

Install dependencies and build

Install the necessary NPM dependencies by running the following commands:

npm install
npm run build

Amazon MQ for RabbitMQ networking deployment options

Public accessibility is the primary networking differentiator when deploying a RabbitMQ broker in AWS. Although the broker operates in the Amazon MQ service account, the networking configuration varies based on this choice.

Public broker

When you deploy a publicly accessible broker, Amazon MQ provisions all networking components in the service account. The service provides a DNS name that resolves to an IP address of the Network Load Balancer (NLB) in that account. This configuration doesn’t support security groups. All security measures must be implemented through the RabbitMQ broker’s authentication and authorization mechanisms. The following diagram shows this communication flow.

Figure-1 DNS resolution of a public Amazon MQ for RabbitMQ broker.

Private broker

A private broker routes networking through a Amazon Virtual Private Cloud (Amazon VPC) in your account. Amazon MQ uses AWS PrivateLink to provision VPC Endpoints, which serve as entry points for broker communication.

The following diagram shows how client applications communicate with RabbitMQ:

  1. The client application connects to Amazon Route 53 Resolver
  2. Route 53 Resolver resolves the DNS name to the VPC Endpoint’s IP address
  3. The client communicates with the broker through PrivateLink
  4. Security groups protect the VPC Endpoint’s Elastic Network Interfaces (ENIs)

Figure-2 DNS resolution of a private Amazon MQ for RabbitMQ broker.

A private broker deployment offers two networking options:

  • Custom VPC configuration – Specify:
    • Subnets for VPC Endpoint creation
    • At least one security group to protect the VPC Endpoints
  • Default VPC configuration – Leave VPC options blank to use:
    • Default VPC
    • Default security group

Amazon MQ for RabbitMQ Lambda event source mapping building blocks

RabbitMQ solutions offer two approaches for message processing:

  • Create a custom client to read messages from broker queues
  • Use Lambda functions with event source mapping (ESM) for automated message retrieval

The ESM is a Lambda service resource that reads the messages from the broker and invokes the Lambda function synchronously. In the remainder of this post, we refer to this Lambda function as listener.

ESM connectivity depends on the following:

For public brokers, ESM uses public connectivity. For private brokers, ESM:

  • Assumes the listener’s IAM Role
  • Creates ENIs in the same subnets as the broker’s VPC Endpoints
  • Uses the same security groups that protect the VPC Endpoints

The listener’s IAM Role must include these Amazon Elastic Compute Cloud (Amazon EC2) permissions:

  • CreateNetworkInterface
  • DeleteNetworkInterface
  • DescribeNetworkInterfaces
  • DescribeSecurityGroups
  • DescribeSubnets
  • DescribeVpcs

To view ESM ENIs:

  1. Open the AWS Management Console
  2. Navigate to EC2 > Network Interfaces
  3. Look for ENIs with the following naming pattern:
    AWS Lambda VPC ENI-armq-<ACCOUNT_ID>-<ESM_ID>-<remainder>

    where:

    • ACCOUNT_ID – The AWS account number containing the ESM
    • ESM_ID – The unique identifier of the ESM

The following image shows example ESM ENIs.

Figure-3 An example list of interfaces that Amazon MQ for RabbitMQ creates for private brokers.

Disabling or deleting the ESM removes the ESM components.

An enabled ESM needs connectivity to the following:

Because the ESM queue polling process follows these steps:

  1. Assumes the listener’s IAM Role
  2. Retrieves RabbitMQ credentials from Secrets Manager
  3. Establishes broker communication
  4. Invokes the listener when messages are present

You have two options to enable private broker connectivity to support the queue polling process:

  1. Deploy VPC endpoints in ESM subnets for:
    • AWS Security Token Service (AWS STS)
    • Secrets Manager
    • Lambda
  2. Deploy NAT gateway in ESM subnets

ESM networking configuration options

The following sections detail ESM networking configurations for different deployment scenarios.

Option 1: Public broker

In this approach all network communication happens on the Amazon MQ service’s side. The ESM, when enabled, uses public connectivity.

To observe the architecture implemented in your account go to the cloned repository root location, make sure that you are signed in with AWS CLI and run the following:

cdk deploy PublicRabbitMqInstanceStack

Option 2: Private broker in a default VPC

Deploying a private RabbitMQ broker without specifying the VPC informs the Amazon MQ service to pick the default VPC for setting up the networking and then the public subnet(s) in that VPC. The default security group is used for securing the broker’s VPC Endpoints.

Creating the ESM provisions dedicated ENIs in the public subnets where the RabbitMQ broker’s VPC Endpoints reside with the default security group applied. The default security group allows itself for inbound traffic on all protocols and full port range, thus the ESM can route traffic through the VPC Endpoint.

Although the subnet is public with internet gateway access, the ESM ENIs operate in private address space, preventing direct communication with AWS services. To enable proper communication, create VPC Endpoints for AWS STS, Secrets Manager, and Lambda. These endpoints allow the ESM to communicate with AWS services through private IP addresses within your VPC. The following diagram shows the complete communication path from the ESM to the broker.

Figure-4 Networking configuration and request flow for a private broker provisioned in the default VPC.

To observe the architecture implemented in your account, go to the cloned repository root location, make sure that you are signed in with AWS CLI, and run the following

cdk deploy PrivateRabbitMqInstanceDefaultVpcStack

Option 3: Private broker in a Custom VPC with NAT

When deploying a private RabbitMQ broker in a custom VPC, specify either a single subnet for a standalone broker or multiple subnets for a cluster deployment. The deployment also needs a security group for the VPC Endpoint ENIs.

Configure the security group with a self-referencing inbound rule on the AMQP port. This configuration enables communication between the ESM and the RabbitMQ VPC Endpoints’ ENIs.

The following diagram shows how ESM resources communicate through networking components when deployed in a private subnet with NAT gateway. This architecture demonstrates the complete communication path from the ESM to the broker.

Figure-5 Networking configuration and request flow for a private broker provisioned in a private VPC subnet with NAT.

To observe the architecture implemented in your account, go to the cloned repository root location, make sure that you are signed in with AWS CLI, and run the following:

cdk deploy PrivateRabbitMqInstanceCustomVpcWithNatStack

Option 4: Private broker in a Custom VPC with isolated subnets

This configuration builds upon the previous architecture but introduces isolated subnets. These subnets restrict all internet connectivity, permitting only internal VPC network traffic. Although the broker networking components mirror Option 3, the isolation introduces more considerations.

The security group still needs an open AMQP port for queue operations, but the subnet isolation prevents the ESM from directly accessing AWS services. To address this limitation, deploy VPC Endpoints for AWS STS, Secrets Manager, and Lambda within the isolated subnets. These endpoints create a private communication path for the ESM to interact with essential AWS services without needing internet access.

The following diagram shows the communication architecture for ESM resources deployed in isolated subnets. It demonstrates how VPC Endpoints enable secure communication between the ESM and AWS services while maintaining network isolation. This architecture makes sure that the ESM can fulfill its message processing responsibilities without compromising security through internet exposure.

Figure-6 Networking configuration and request flow for a private broker provisioned in an isolated VPC subnet.

To observe the architecture implemented in your account, go to the cloned repository root location, make sure that you are signed in with AWS CLI, and run the following:

cdk deploy PrivateRabbitMqInstanceCustomVpcIsolatedSubnetStack

Option 5: Private broker in a Custom VPC with public subnets

The final configuration places the broker in public subnets while maintaining the core deployment requirements from the previous options. Despite the public subnet placement, the ESM’s networking behavior presents an important consideration: ESM ENIs operate in private address space, preventing direct internet communication even with an internet gateway present.

This architecture necessitates VPC Endpoints for AWS service communication, similar to Option 2. Any attempts to route ESM traffic through the internet gateway fail because the ENIs operate in private address space. Understanding this limitation is crucial for proper deployment planning.

The following diagram shows the ESM communication architecture in public subnets. Despite the different subnet type, this configuration mirrors the isolated subnet approach in its use of VPC Endpoints. These endpoints enable the ESM to communicate with AWS STS, Secrets Manager, and Lambda services through private, secure connections within the VPC.

Figure-7 Networking configuration and request flow for a private broker provisioned in a public VPC subnet.

To observe the architecture implemented in your account, go to the cloned repository root location, make sure that you are signed in with AWS CLI, and run the following:

cdk deploy PrivateRabbitMqInstanceCustomVpcPublicSubnetStack

Cleaning up

To prevent unexpected AWS charges, remove resources you’ve created. The following AWS CDK command helps you safely remove all deployed resources:

cdk destroy --all

Conclusion

This post explored the relationship between AWS Lambda event source mapping and RabbitMQ networking configurations. We examined various deployment scenarios, from public brokers to isolated subnets, each presenting unique considerations for secure and effective implementation.

Understanding these networking patterns enables you to make informed architectural decisions when deploying Amazon MQ for RabbitMQ with Lambda event source mapping. Whether choosing public accessibility or implementing private networking with VPC Endpoints, understanding the consequences of choosing specific networking configurations allows you to apply security best practices while meeting your application’s messaging needs. As you implement these patterns, consider your specific security requirements and operational needs to choose the most appropriate configuration for your use case.

Take the next step in optimizing your serverless messaging architecture. Dive in to the AWS documentation, experiment with the RabbitMQ and Lambda integration patterns discussed, and discover how these networking configurations can elevate the security and performance of your own applications. Start implementing these strategies today to build more robust, scalable solutions.
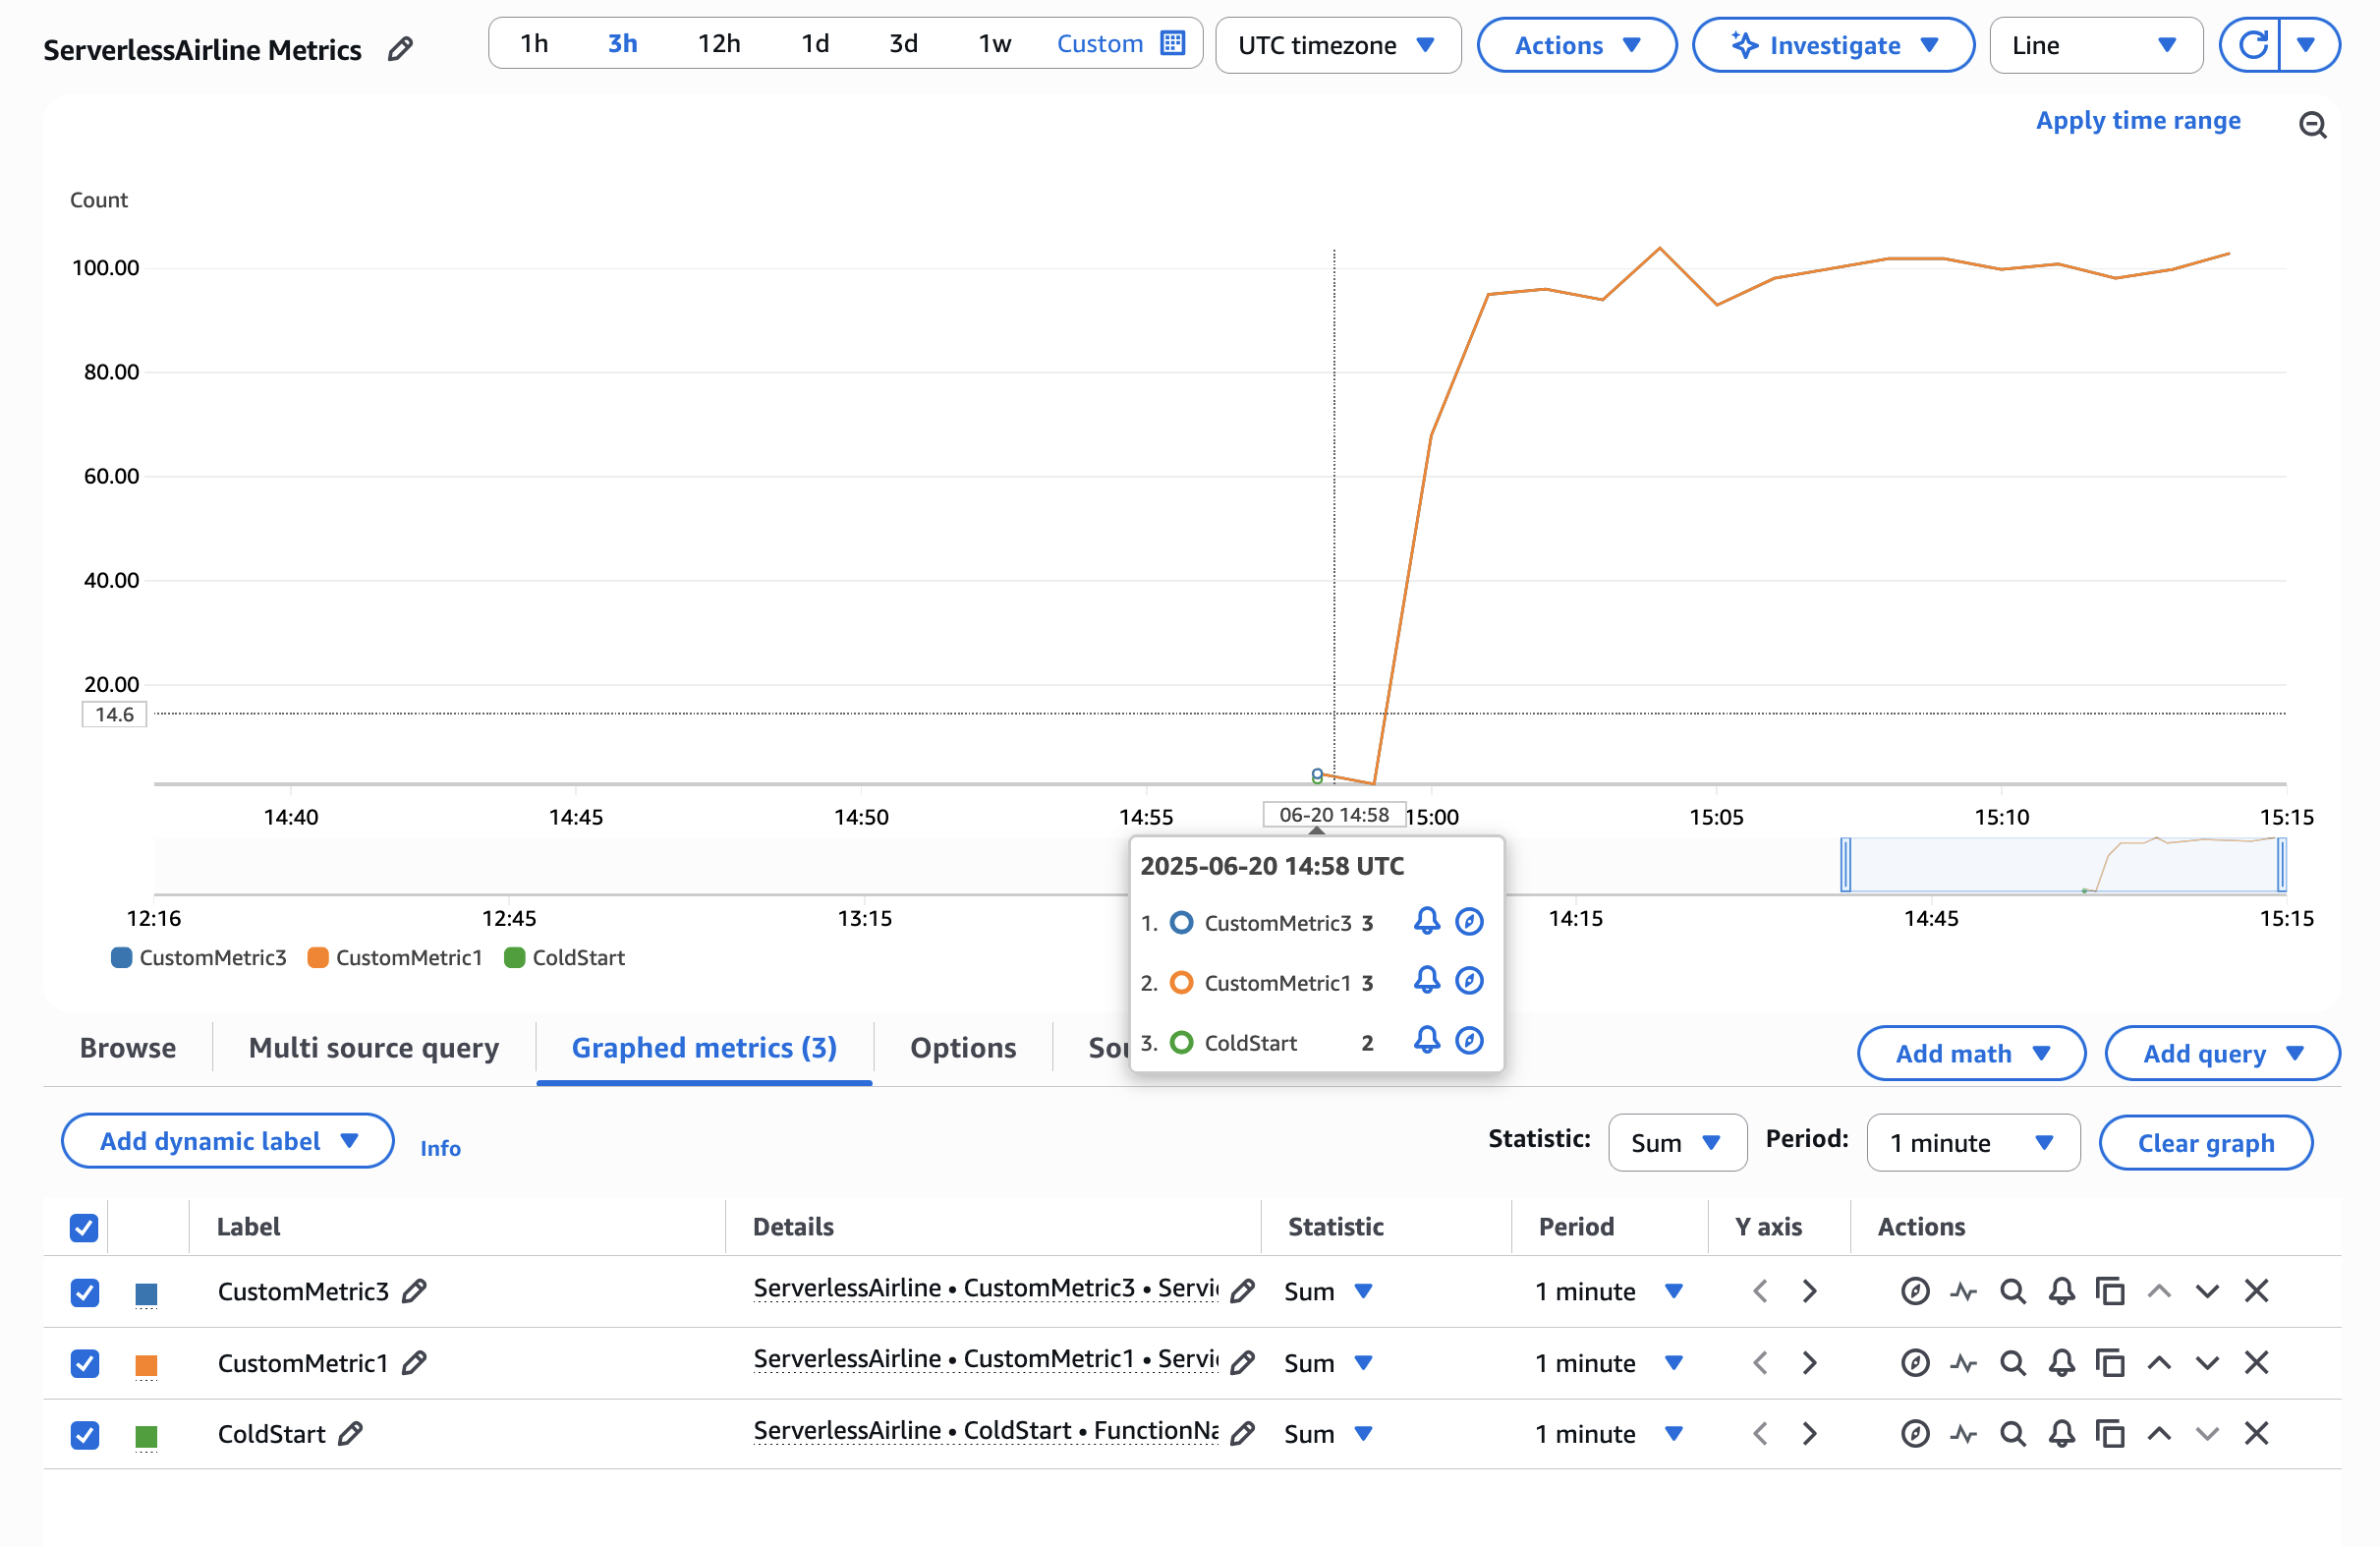
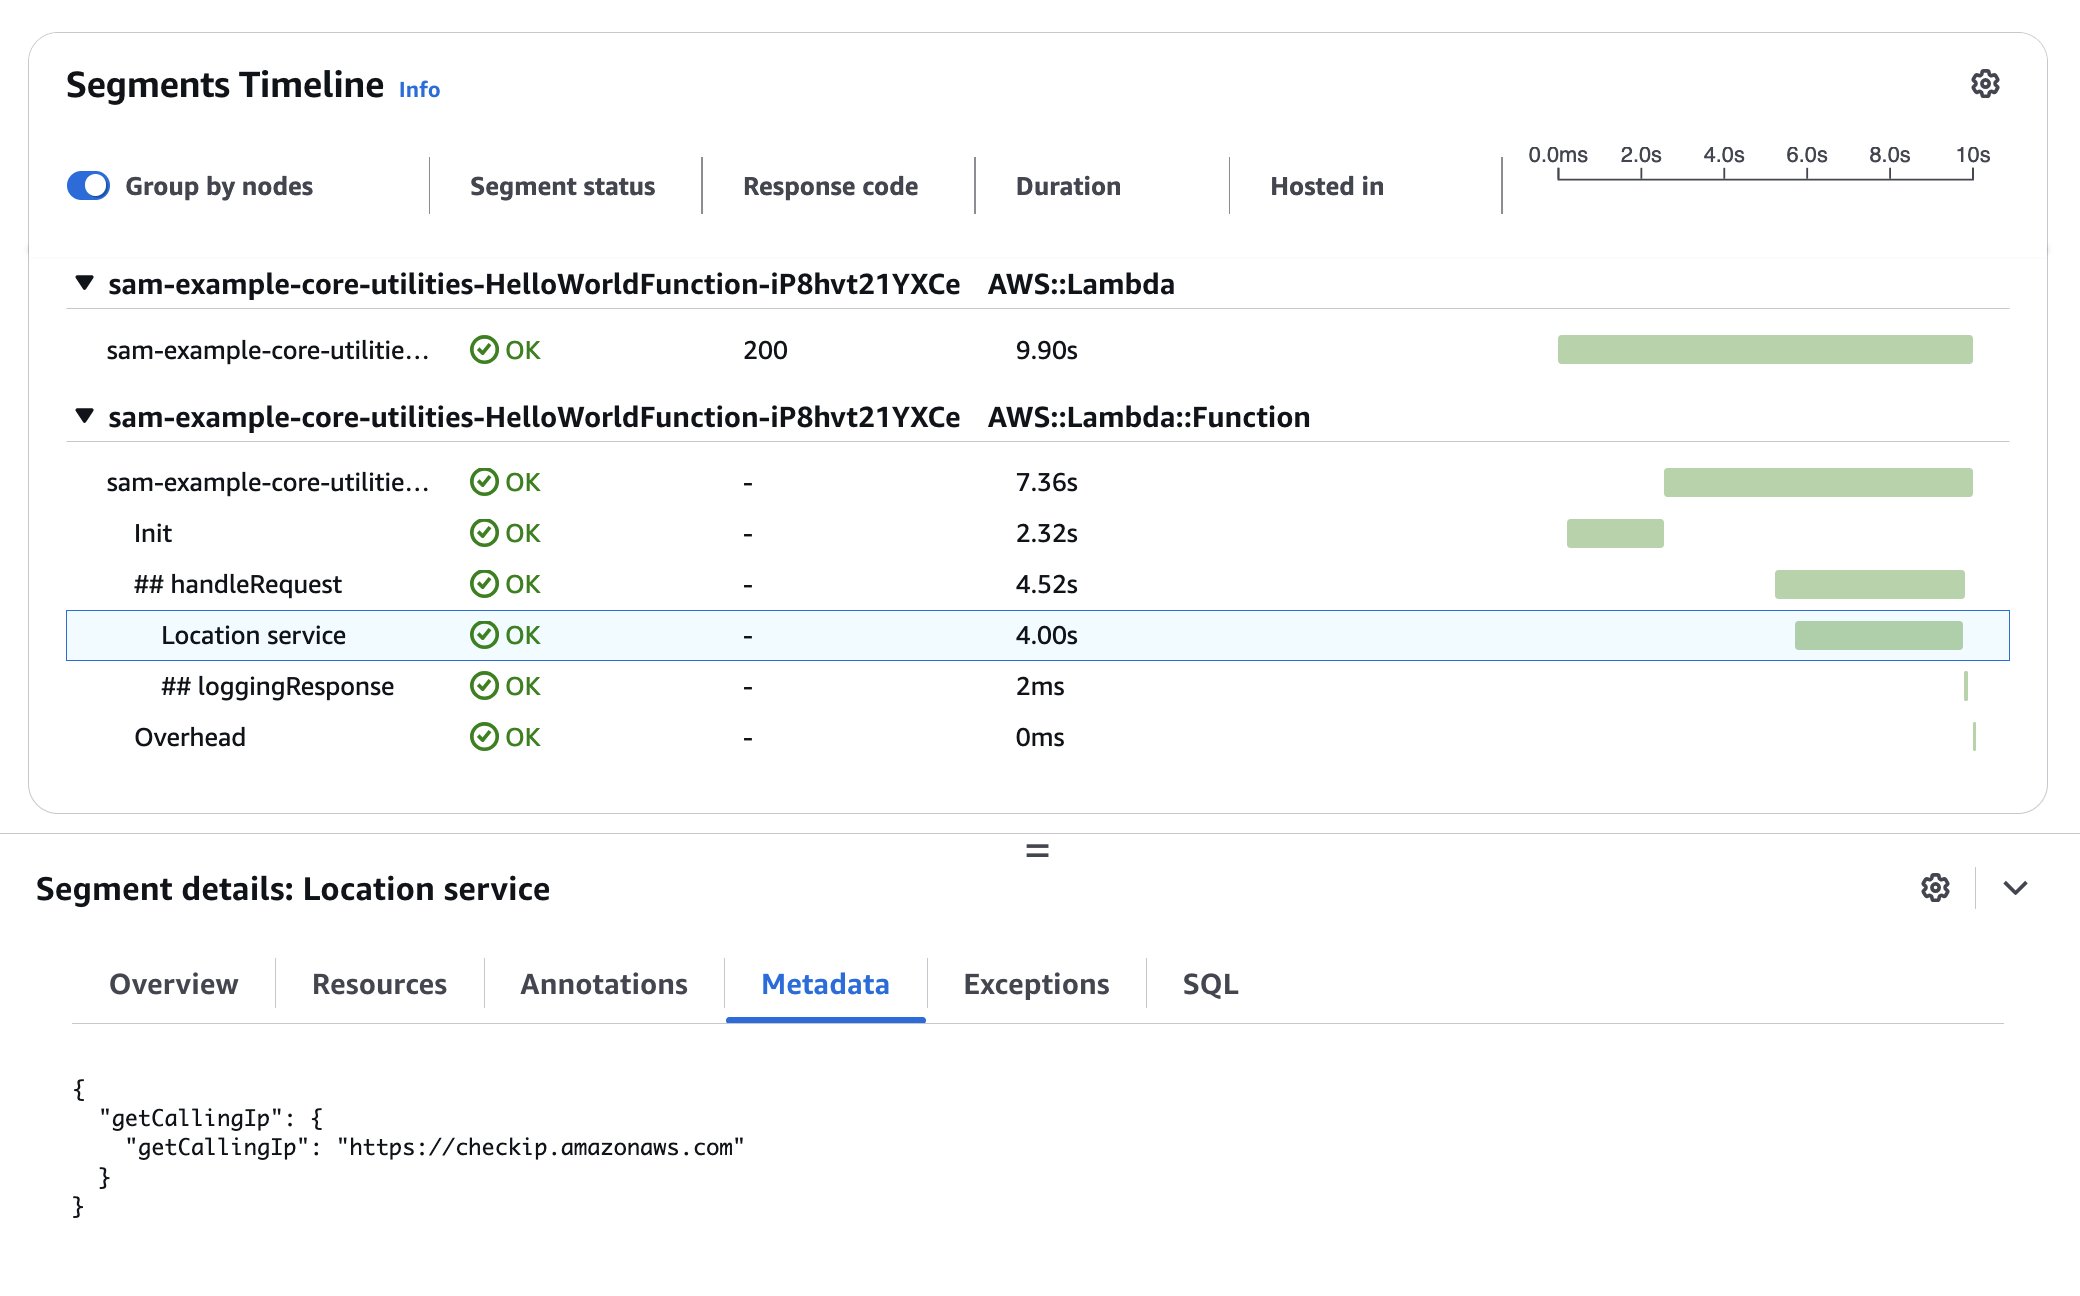
AWS Weekly Roundup: AWS re:Inforce 2025, AWS WAF, AWS Control Tower, and more (June 16, 2025)

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-aws-reinforce-2025-aws-waf-aws-control-tower-and-more-june-16-2025/

Today marks the start of AWS re:Inforce 2025, where security professionals are gathering for three days of technical learning sessions, workshops, and demonstrations. This security-focused conference brings together AWS security specialists who build and maintain the services that organizations rely on for their cloud security needs.

AWS Chief Information Security Officer (CISO) Amy Herzog will deliver the conference keynote along with guest speakers who will share new security capabilities and implementation insights. The event offers multiple learning paths with sessions designed for various technical roles and expertise levels. Many of my colleagues from across AWS are leading hands-on workshops, demonstrating new security features, and facilitating community discussions. For those unable to join us in Philadelphia, the keynote and innovation talks will be viewable by livestream during the event, and available to watch on demand after the event. Look out for the key announcements and technical insights from the conference in upcoming posts!

Let’s look at last week’s new announcements.

Last week’s launches
Here are the launches that got my attention.

Extend Amazon Q Developer IDE plugins with MCP tools – Amazon Q Developer now supports Model Context Protocol (MCP) in its integrated development environment (IDE) plugins, helping developers integrate external tools for enhanced contextual development workflows. You can now augment the built-in tools with any MCP server that supports the stdio transport layer. These servers can be managed within the Amazon Q Developer user interface. This makes it easy to add, remove, and modify tool permissions. The integration enables more customized responses by orchestrating tasks across both native and MCP server-based tools. MCP support is available in Visual Studio Code and JetBrains IDE plugins, as well as in the Amazon Q Developer command line interface (CLI), with detailed documentation and implementation guides available in the Amazon Q Developer documentation.

AWS WAF now supports automatic application layer DDoS protection – AWS has enhanced its application layer (L7) distributed denial of service (DDoS) protection capabilities with faster automatic detection and mitigation that responds to events within seconds. This AWS Managed Rules group automatically detects and mitigates DDoS attacks of any duration to keep applications running on Amazon CloudFront, Application Load Balancer, and other AWS WAF supported services available to users. The system establishes a baseline within minutes of activation using machine learning (ML) models to detect traffic anomalies, then automatically applies rules to address suspicious requests. Configuration options help you customize responses such as presenting challenges or blocking requests. The feature is available to all AWS WAF and AWS Shield Advanced subscribers in all supported AWS Regions, except Asia Pacific (Thailand), Mexico (Central), and China (Beijing and Ningxia). To learn more about AWS WAF application layer (L7) DDoS protection, visit the AWS WAF documentation or the AWS WAF console.

AWS Control Tower now supports service-linked AWS Config managed AWS Config rules – AWS Control Tower now deploys service-linked AWS Config rules directly in managed accounts, replacing the previous CloudFormation StackSets deployment method. This change improves deployment speed when enabling service-linked AWS Config rules across multiple AWS Control Tower managed accounts and Regions. These service-linked rules are managed entirely by AWS services and can’t be edited or deleted by users. This helps maintain consistency and prevent configuration drift. AWS Control Tower Config rules detect resource noncompliance within accounts and provide alerts through the dashboard. You can deploy these controls using the AWS Control Tower console or AWS Control Tower control APIs.

Powertools for AWS Lambda introduces Bedrock Agents Function utility – The new Amazon Bedrock Agents Function utility in Powertools for AWS Lambda simplifies building serverless applications integrated with Amazon Bedrock Agents. This utility helps developers create AWS Lambda functions that respond to Amazon Bedrock Agents action requests with built-in parameter injection and response formatting, eliminating boilerplate code. The utility seamlessly integrates with other Powertools features like Logger and Metrics, making it easier to build production-ready AI applications. This integration improves the developer experience when building agent-based solutions that use AWS Lambda functions to process actions requested by Amazon Bedrock Agents. The utility is available in Python, TypeScript, and .NET versions of Powertools.

Announcing open sourcing pgactive: active-active replication extension for PostgreSQL – Pgactive is a PostgreSQL extension that enables asynchronous active-active replication for streaming data between database instances, and AWS has made it open source. This extension provides additional resiliency and flexibility for moving data between instances, including writers located in different Regions. It helps maintain availability during operations like switching write traffic. Building on PostgreSQL’s logical replication features, pgactive adds capabilities that simplify managing active-active replication scenarios. The open source approach encourages collaboration on developing PostgreSQL’s active-active capabilities while offering features that streamline using PostgreSQL in multi-active instance environments. For more information and implementation guidance, visit the GitHub repository.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

We launched existing services and instance types in additional Regions:

Other AWS events
Check your calendar and sign up for upcoming AWS events.

AWS GenAI Lofts are collaborative spaces and immersive experiences that showcase AWS expertise in cloud computing and AI. They provide startups and developers with hands-on access to AI products and services, exclusive sessions with industry leaders, and valuable networking opportunities with investors and peers. Find a GenAI Loft location near you and don’t forget to register.

AWS Summits are free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Milano (June 18), Shanghai (June 19 – 20), Mumbai (June 19) and Japan (June 25 – 26).

Browse all upcoming AWS led in-person and virtual events here.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Esra

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

Validating event payload with Powertools for AWS Lambda (TypeScript)

Post Syndicated from Alexander Schüren original https://aws.amazon.com/blogs/compute/validating-event-payload-with-powertools-for-aws-lambda-typescript/

In this post, learn how the new Powertools for AWS Lambda (TypeScript) Parser utility can help you validate payloads easily and make your Lambda function more resilient.

Validating input payloads is an important aspect of building secure and reliable applications. This ensures that data that an application receives can gracefully handle unexpected or malicious inputs and prevent harmful downstream processing. When writing AWS Lambda functions, developers need to validate and verify the payload and ensure that specific fields and values are correct and safe to process.

Powertools for AWS Lambda is a developer toolkit available in Python, NodeJS/TypeScript, Java and .NET. It helps implement serverless best practices and increase developer velocity. Powertools for AWS Lambda (TypeScript) is introducing a new Parser utility to help developers more easily implement validation in their Lambda functions.

Why payload validation matters

Validating payloads can make your Lambda functions more resilient. Payloads that combine both technical and business information can also be challenging to validate. This requires writing validation logic inside your Lambda function code.This could range from a few if-statements to check payload values to a complex series of validation steps based on custom business logic. You may need to separate the validation of the technical information of payload like AWS Region, accountId, event source and business information inside the event such as productId and payment details.

It can be challenging to know the structure and the values of the event object and how to extract the relevant information. For example, an Amazon SQS event has a body field with a string value, which can be a JSON document. Amazon EventBridge has an object in the detail field that you can read directly without further transformation. You may need to decompress, decode, transform, and validate the payload inside a specific field. Understanding the many transformation layers can be complex, especially if your event object is a result of multiple service invocations.

Using the Powertools for AWS Lambda (TypeScript) Parser Utility

Powertools for AWS Lambda (TypeScript) is a modular library. You can selectively install features such as Logger, Tracer, Metrics, Batch Processing, Idempotency, and more. You can use Powertools for AWS Lambda in both TypeScript and JavaScript code bases. The new Parser utility simplifies validation and uses the popular validation library, Zod.

You can use parser as method decorator, with middyjs middleware or manually in all Lambda provided NodeJS runtimes

To use the utility, install the Powertools parser utility and Zod (<v3.x) using NPM or any package manager of your choice:

npm install @aws-lambda-powertools/parser zod@~3

You can define your schema using Zod. Here is an example of a simple order schema for validating events:

import { z } from 'zod';
const orderSchema = z.object({
    id: z.number().positive(),
	description: z.string(),
	items: z.array(
	    z.object({
		    id: z.number().positive(),
			quantity: z.number(),
			description: z.string(),
			})
		),
	});
export { orderSchema };

This order schema defines id, description and a list of items. You can specify the value types from simple numeric, narrow it down to positive or literal, or more complex like unition, array or even other schema. Zod offers an extensive list of value types that you can use.

Add the parser decorator to your handler function and set the schema parameter and use this schema to parse the event object.

import type {Context} from 'aws-lambda';
import type {LambdaInterface} from '@aws-lambda-powertools/commons/types';
import {parser} from '@aws-lambda-powertools/parser';
import {z} from 'zod';
import {Logger} from '@aws-lambda-powertools/logger';

const logger = new Logger();

const orderSchema = z.object({
    id: z.number().positive(),  
	description: z.string(),  
	items: z.array(
	    z.object({
		    id: z.number().positive(),
			quantity: z.number(),
			description: z.string(),
		})
	),
});

type Order = z.infer<typeof orderSchema>;

class Lambda implements LambdaInterface {
    @parser({schema: orderSchema})  
	public async handler(event: Order, _context: Context): Promise<void> {
	    // event is now typed as Order    
		for (const item of event.items) {      
		    logger.info('Processing item', {item});
			// process order item from the event
		}
	}
}
	
const myFunction = new Lambda();

export const handler = myFunction.handler.bind(myFunction);

Note that z.infer helps to extract the Order type from the schema, which improves development experience with autocomplete when using TypeScript. Zod parses the entire object, including nested fields, and reports all the errors combined, instead of returning only the first error.

Using built-in schema for AWS services

A more common scenario is to validate events from AWS Services that trigger Lambda functions, including Amazon SQS, Amazon EventBridge and many more. To make this easier Powertools includes pre-built schema for AWS events that you can use.

To parse an incoming Amazon EventBridge event, set the built-in schema in your parser configuration:

import {LambdaInterface} from '@aws-lambda-powertools/commons/types';
import {Context} from 'aws-lambda';
import {parser} from '@aws-lambda-powertools/parser';
import {EventBridgeSchema} from '@aws-lambda-powertools/parser/schemas';
import type {EventBridgeEvent} from '@aws-lambda-powertools/parser/types';

class Lambda implements LambdaInterface {  
    @parser({schema: EventBridgeSchema})  
	public async handler(event: EventBridgeEvent, _context: Context): Promise<void> {    
	    // event is parsed but the detail field is not specified  
	}
}

const myFunction = new Lambda();

export const handler = myFunction.handler.bind(myFunction);

The event object is parsed and validated during runtime and the TypeScript type EventBridgeEvent helps you understand the structure and access the fields during development. In this example, you only parse the EventBridge event object, so the detail field can be an arbitrary object.

You can also extend the built-in EventBridge schema and override the detail field with your custom oderSchema.

import {LambdaInterface} from '@aws-lambda-powertools/commons/types';
import {Context} from 'aws-lambda';
import {parser} from '@aws-lambda-powertools/parser';
import {EventBridgeSchema} from '@aws-lambda-powertools/parser/schemas';
import {z} from 'zod';

const orderSchema = z.object({  
    id: z.number().positive(),  
	description: z.string(),  
	items: z.array(
	    z.object({
		    id: z.number().positive(),      
			quantity: z.number(),      
			description: z.string(),
		}), 
	),
});

const eventBridgeOrderSchema = EventBridgeSchema.extend({  detail: orderSchema,});

type EventBridgeOrder = z.infer<typeof eventBridgeOrderSchema>;

class Lambda implements LambdaInterface {  
    @parser({schema: eventBridgeOrderSchema})  public async handler(event: EventBridgeOrder, _context: Context): Promise<void> {
	    // event.detail is now parsed as orderSchema  
	}
}

const myFunction = new Lambda();

export const handler = myFunction.handler.bind(myFunction);

The parser validates the full structure of the entire EventBridge event including the custom business object. Use .extend or other Zod schema functions to change any field of the built-in schema and customize the payload validation.

Using envelopes with custom schema

In some cases, you only need the custom portion of the payload, for example, the detail field of the EventBridge event or the body of SQS records. This requires you to parse the event schema manually, extract the required field, and then parse it again with the custom schema. This is complex as you must know the exact payload field and how to transform and parse it.

Powertools Parser utility helps solve this problem with Envelopes. Envelopes are schema objects with built-in logic to extract custom payloads.

Here is an example of the EventBridgeEnvelope of how it works:

import {LambdaInterface} from '@aws-lambda-powertools/commons/types';
import {Context} from 'aws-lambda';
import {parser} from '@aws-lambda-powertools/parser';
import {EventBridgeEnvelope} from '@aws-lambda-powertools/parser/envelopes';
import {z} from 'zod';

const orderSchema = z.object({  
    id: z.number().positive(), 
	description: z.string(),  
	items: z.array(    
	    z.object({      
		    id: z.number().positive(),      
			quantity: z.number(),      
			description: z.string(),
		}), 
	),
});

type Order = z.infer<typeof orderSchema>;

class Lambda implements LambdaInterface {  
    @parser({schema: orderSchema, envelope: EventBridgeEnvelope})  public async handler(event: Order, _context: Context): Promise<void> {
        // event is now typed as Order inferred from the orderSchema  
    }
}

const myFunction = new Lambda();

export const handler = myFunction.handler.bind(myFunction);

By setting schema and envelope, the parser utility knows how to combine both parameters, extract, and validate the custom payload from the event. Powertools Parser transforms the event object according to the schema definition so you can focus on your business-critical part of the code inside the handler function.

Safe parsing

If the object does not match the provided Zod schema, by default, the parser throws ParserError. If you require control over validation errors and need to implement custom error handling, use the safeParse option.

Here is an example how to capture failed validations as a metric in your handler function:

import {Logger} from "@aws-lambda-powertools/logger";
import {LambdaInterface} from "@aws-lambda-powertools/commons/types";
import {parser} from "@aws-lambda-powertools/parser";
import {orderSchema} from "../app/schema";import {z} from "zod";
import {EventBridgeEnvelope} from "@aws-lambda-powertools/parser/envelopes";
import {Metrics, MetricUnit} from "@aws-lambda-powertools/metrics";
import {ParsedResult, EventBridgeEvent} from "@aws-lambda-powertools/parser/types";

const logger = new Logger();

const metrics = new Metrics();

type Order = z.infer<typeof orderSchema>;

class Lambda implements LambdaInterface {  

    @metrics.logMetrics() 
	@parser({schema: orderSchema, envelope: EventBridgeEnvelope, safeParse: true})  
	public async handler(event: ParsedResult<EventBridgeEvent, Order>, _context: unknown): Promise<void> {
	    if (!event.success) {      
		    // failed validation      
			metrics.addMetric('InvalidPayload', MetricUnit.Count, 1);      
			logger.error('Invalid payload', event.originalEvent);    
		} else {      
		    // successful validation      
			for (const item of event.data.items) {        
			    logger.info('Processing item', item);        
				// event.data is typed as Order      
			}   
		}  
	}
}

const myFunction = new Lambda();

export const handler = myFunction.handler.bind(myFunction);

Setting safeParse option to true does not throw an error, but returns a modified event object that has a success flag and either error or data fields, depending on the validation result. You can then create custom error handling, for example incrementing InvalidPayload metric and access the originalEvent to log an error.

For successful validations, you can access the data field and process the payload. Note that the event object type is now ParsedResult with the EventBridgeEvent as input and Order as output types.

Custom validations

Sometimes you may require more complex business rules for your validation. Because Parser built-in schemas are Zod objects, you can customize the validation by applying .extend, .refine , .transform and other Zod operators. Here is an example of complex rules for the orderSchema:

import {z} from 'zod';

const orderSchema = z.object({
    id: z.number().positive(),  
	description: z.string(),  
	items: z.array(z.object({
	    id: z.number().positive(),    
		quantity: z.number(),    
		description: z.string(),  
	})).refine((items) => items.length > 0, {
	    message: 'Order must have at least one item',  
	}),
})  
    .refine((order) => order.id > 100 && order.items.length > 100, {
	    message:      'All orders with more than 100 items must have an id greater than 100', 
	});

Use .refine on items field to check if there is at least one item in the order. You can also combine multiple fields, here order.id and order.items.length, to have a specific rule for orders with more than 100 items. Keep in mind that .refine runs during the validation step and .transform will be applied after the validation. This allows you to change the shape of the data to normalize the output.

Conclusion

Powertools for AWS Lambda (TypeScript) is introducing a new Parser utility that makes it easier to add validation to your Lambda functions. By relying on the popular validation library Zod, Powertools offers an extensive set of built-in schemas for popular AWS service integrations including Amazon SQS, Amazon DynamoDB, Amazon EventBridge. Developers can use these schemas to validate their event payloads and also customize them according to their business needs.

Visit the documentation to learn more and join our Powertools community Discord to connect with like-minded serverless enthusiasts.

Optimizing ODCR usage through AI-powered capacity insights

Post Syndicated from Ankush Goyal original https://aws.amazon.com/blogs/compute/optimizing-odcr-usage-through-ai-powered-capacity-insights/

Efficient resource management is crucial for organizations seeking to optimize cloud costs while making sure of seamless access to compute capacity. Amazon Elastic Compute Cloud (Amazon EC2) On-Demand Capacity Reservations (ODCRs) provide the flexibility to reserve compute capacity within a specific Availability Zone (AZ) for any duration. This makes sure that critical workloads always have the necessary resources available, minimizing the risk of capacity shortages.

However, managing ODCRs across multiple teams and accounts presents several challenges:

  • Limited visibility across teams: In large organizations, tracking ODCR usage across teams and business units can be difficult, often leading to underused or duplicate reservations.
  • Complexity in optimization: Without clear insights, adjusting, releasing, or modifying reservations to align with changing workloads becomes a cumbersome process.
  • Cost management challenges: Unused or oversized ODCRs contribute to unnecessary expenses, making it essential to continuously monitor and optimize usage.

In this post, we demonstrate how Amazon Bedrock Agents can help organizations gain actionable insights into ODCR usage across their Amazon Web Services (AWS) environment. Unlike traditional approaches that rely on predefined patterns or manual tracking, this solution dynamically retrieves the latest ODCR usage data and provides intelligent, query-based recommendations to fulfill the capacity needs. This solution is serverless and pay-per-use and incurs minimal operational cost.

This approach allows IT leaders, cloud architects, and finance teams to optimize reservations, control costs, and enhance overall resource management—without the complexity of traditional analysis methods.

Solution overview

This solution addresses two specific use cases:

  1. The team must create a new ODCR to accommodate an upcoming project.
  2. The team needs to expand the capacity of their existing ODCR.

The system consists of three essential components:

  • ODCRSupervisorAgent: Functions as the main coordinator, handling user inquiries and managing requests to specialized subordinate agents.
  • CapacityPlanningAgent: Reviews existing ODCRs throughout the organization, recommending SPLIT and MOVE operations to optimize capacity allocation for new projects.
  • AugmentationAgent: Identifies opportunities to increase existing ODCR capacity by recommending MOVE operations from other organizational ODCRs.

The following figure shows the high-level architecture for this solution.

The system architecture uses AWS services for comprehensive ODCR management, as shown in the following figure. The platform combines Amazon Cognito for authentication, AWS Amplify for front-end delivery, and AWS Lambda for serverless computing. AWS Resource Explorer enables efficient discovery and tracking of ODCRs across AWS Regions, while Lambda functions periodically query Resource Explorer to retrieve detailed ODCR information and usage metrics. AWS Identity and Access Management (IAM) plays a crucial role in securing the system, managing fine-grained access controls and permissions across all components. Amazon Bedrock Agents and its multi-agent capabilities generate intelligent recommendations through coordinated agent interactions, allowing organizations to optimize ODCR usage and implement data-driven capacity planning strategies.

How the solution functions

At the heart of this system is an Amazon Bedrock Agent powered by Action Groups, which map user queries to backend tasks using Lambda. These Lambda functions act as the system’s intelligence layer: fetching, filtering, and formatting ODCR data for the agent to reason over. The following three Lambda functions are deployed as part of the AWS CloudFormation template:

get_az_mapping_info Lamba function: This Lambda function takes an AWS account ID and Region as input. It returns a mapping of AZ names to their corresponding AZ IDs for that account and AWS Region. This helps the Capacity Planning Agent align AZs across accounts.

find_eligiable_odcrs Lambda function: This Lambda function supports the Capacity Planning Agent by identifying suitable ODCRs that meet the specified instance type and AZ. It uses Resource Explorer to search for ODCRs across the organization. Then, the function assumes cross-account roles to access ODCRs in different AWS accounts to gather detailed information. After retrieving the necessary data, it filters the ODCRs based on instance type, tenancy, and AZ. Finally, it returns a formatted list of eligible ODCRs, which are sourced from either the specified account or an alternative account with adequate capacity.

find_eligible_odcrs_for_move Lambda function: This Lambda function assists the Augmentation Agent by finding all capacity reservations within the same account as the specified ODCR. It uses Resource Explorer to discover ODCRs and, when necessary, assumes cross-account roles to gather ODCR information. The function filters ODCRs based on matching instance type, tenancy, and AZ, then returns a formatted list of eligible ODCRs that can provide more capacity through MOVE operations.

Each Lambda function receives structured inputs from the Amazon Bedrock Agent, executes its designated task, and returns structured responses. Then, these responses are used by the agent to generate intelligent, actionable answers to user queries.

Together, these Lambda functions extend the capabilities of the Amazon Bedrock Agent by integrating with external data sources and automating complex ODCR management logic—allowing the system to deliver accurate, dynamic recommendations.

Prerequisites

You must have the following in place to implement the solution in this post:

Deploy solution resources using CloudFormation

This solution is designed to be deployed in a single Region. If deploying outside us-east-1, then you must modify the CloudFormation parameters to reference the correct FM version and adjust for Regional availability, such as any necessary cross-Region inference profile configurations.

  • Deploy the Cross Account IAM Role template: To access ODCR data across your Organization, deploy a CloudFormation StackSet from your payer account. During deployment, you must provide the account number where you plan to deploy the ODCR solution. This is the same account number that you used as delegate account for Resource Explorer under the prerequisites. This account number is added to the trust policy of the IAM role, allowing the solution in that account to assume the role created by the StackSet. The deployment automatically provisions a standardized IAM role with the necessary permissions (for example ec2:DescribeCapacityReservations and ec2:DescribeAvailabilityZones) in each target account.
  • Deploy the ODCR Solution template: Deploy the provided template in the delegated administrator account that you chose for Resource Explorer. This sets up the core components of the solution and integrates with your payer account for organization-wide ODCR insights.

Resources deployed by the CloudFormation template

After you have deployed the CloudFormation template, the following AWS resources are created in your account.

Cross Account IAM Role template

  • IAM resource
    • CrossAccountODCRAccessRole

ODCR Solution template

  • Amazon Cognito resources:
    • User Pool: ODCRAgentUserPool
    • App Client: ODCRAgentApp
    • Identity Pool: odcr-identity-pool
    • Groups: ODCRAdmins
    • User: ODCR User
  • IAM resources:
    • IAM roles:
      • GetAZMappingFunctionRole
      • LambdaODCRAccessRole
      • BedrockAgentExecutionRole
      • ODCRSupervisorAgentExecutionRole
      • CognitoAuthRole
  • Lambda functions:
    • get_az_mapping_info
    • find_eligible_odcrs
    • find_eligible_odcrs_for_move
  • Amazon Bedrock Agents
    • ODCRSupervisorAgent
    • CapacityPlanningAgent with action groups:
      • get_az_mapping_info
      • find_eligible_odcrs
    • AugmentationAgent with action group:
      • find_eligible_odcrs_for_move

After you deploy the final CloudFormation template, copy the following from the Outputs tab on the CloudFormation console to use during the configuration of your application after it’s deployed in Amplify:

  • AWSRegion
  • BedrockAgentAliasId
  • BedrockAgentId
  • BedrockAgentName
  • IdentityPoolId
  • UserPoolClientId
  • UserPoolId

The following screenshot shows you what the Outputs tab looks like.

Deploy the Amplify application for front-end

You need to manually deploy the Amplify application using the front-end code found on GitHub. Complete the following steps, as shown in the following figure:

  1. Download the front-end code AWS-Amplify-Frontend.zip from GitHub.
  2. Use the .zip file to manually deploy the application in Amplify.
  3. Return to the Amplify page and use the domain that it automatically generated to access the application.

After completing these steps, your environment is ready to analyze ODCR usage and receive recommendations powered by Amazon Bedrock Agents.

Solution walkthrough

After deploying the application in Amplify, return to the Amplify console. Use the auto-generated domain URL shown there to access the front-end. Upon accessing the application URL, you’re prompted to provide information related to Amazon Cognito and Amazon Bedrock Agents. This information is necessary to securely authenticate users and allow the front end to interact with the Amazon Bedrock Agent. It enables the application to manage user sessions and make authorized API calls to AWS services on behalf of the user.

You can enter information with the values that you collected from the CloudFormation stack outputs, as shown in the following screenshot:

A temporary password was automatically generated during deployment and sent to the email address provided when launching the CloudFormation template. At first sign-in, you’re prompted to reset your password.When you’re signed in, you can begin interacting with the application to analyze and manage your ODCR usage. The interface supports natural language queries to streamline capacity planning. The following are some example questions that you can ask:

  • I require [X units] of capacity for the [INSTANCE TYPE] instance type in Availability Zone [AZ ID], within account [ACCOUNT NUMBER]. Could you please advise if there are any existing On-Demand Capacity Reservations (ODCRs) that can fulfill this requirement? Additionally, what operations would be necessary to utilize the available capacity?

  • I have a requirement to add [X additional units] of capacity to an existing On-Demand Capacity Reservation with ID [cr-0012abcd123456789]. Could you please advise on the steps or operations required to fulfill this request?

Cleaning up

If you decide to discontinue using this solution, then you can follow these steps to remove it, its associated resources deployed using CloudFormation, and the Amplify deployment:

  1. Delete the CloudFormation StackSet:
    1. On the CloudFormation console, choose StackSets in the navigation pane.
    2. Locate your StackSet for the Cross-Account IAM Role (you assigned a name to it).
    3. Choose Delete stacks from StackSet to remove all stack instances.
    4. After all instances are deleted, choose StackSet.
    5. Choose Delete StackSet from the Actions menu.
  2. Delete the CloudFormation stack:
    1. On the CloudFormation console, choose Stacks in the navigation pane.
    2. Locate the stack you created during the deployment process (you assigned a name to it).
    3. Choose the stack and choose Delete.
  3. Delete the Amplify application and its resources. For instructions, refer to Clean Up Resources.

Conclusion

In this post, we demonstrated how to use Amazon Bedrock Agents and AWS services to build an intelligent ODCR management solution. Combining AWS Resource Explorer for organization-wide visibility, Amazon Bedrock Agents for intelligent recommendations, and a secure front-end powered by AWS Amplify, organizations can now make data-driven decisions about their capacity reservations. This solution helps teams optimize ODCR usage, reduce costs, and efficiently manage compute capacity across their AWS Organization. The artificial intelligence (AI)-powered approach eliminates manual tracking and analysis, allowing teams to focus on strategic capacity planning rather than operational overhead.

Get started today by deploying this solution in your AWS environment, and unlock the power of AI-driven capacity insights for more efficient ODCR management.

How Launchpad from Pega enables secure SaaS extensibility with AWS Lambda

Post Syndicated from Anton Aleksandrov original https://aws.amazon.com/blogs/architecture/how-launchpad-from-pega-enables-secure-saas-extensibility-with-aws-lambda/

Large organizations increasingly adopt software as a service (SaaS) solutions to focus on business priorities, reduce infrastructure management overhead, and optimize costs. These organizations expect SaaS vendors to provide customizability facilities for tailoring the solution behavior according to their needs. Although traditional approaches like feature flags and webhooks offer some flexibility, they often fall short of providing a high degree of customizability. A new emerging pattern in this space is tenant-supplied custom code execution, which allows tenants to inject their own code into specific workflow points, enabling deep customization while preserving the core SaaS solutions’ integrity and security.

In this post, we share how Pegasystems (Pega) built Launchpad, its new SaaS development platform, to solve a core challenge in multi-tenant environments: enabling secure customer customization. By running tenant code in isolated environments with AWS Lambda, Launchpad offers its customers a secure, scalable foundation, eliminating the need for bespoke code customizations.

Solution overview

Launchpad, which is built on AWS, is an end-to-end platform on which software providers can build, launch, and operate workflow-centric B2B SaaS applications and AI solutions. It provides a managed, secure, scalable cloud environment for hosting multi-tenant applications and data. It accelerates the build experience with generative AI-powered low code tools, prebuilt capabilities, and subscriber-level configuration. Being a multi-tenant platform at its core, Launchpad had to maintain stringent isolation across tenants in its architecture.

One of the requirements Launchpad had was to allow their tenants to augment the workflows natively by providing custom code. Some common scenarios included communicating with external systems with proprietary non-industry-standard protocols, reuse of existing business logic, and SDK-based custom code development.

The solution necessitated the ability for tenants to provide custom code that would implement the required business logic, which Launchpad would be executing. This required architecting a secure runtime environment for custom code execution that maintains the highest degree of cross-tenant isolation within the multi-tenant architecture, at the same time allowing sufficient access to platform APIs and services. It was essential to build an architecture that would decouple the environment running tenant code from the core SaaS platform, as illustrated in the following diagram.

Architecting the solution topology

To achieve the required high level of compute isolation for running code provided by different tenants, Launchpad has adopted Lambda functions in its architecture as the secure ephemeral compute environment. Each untrusted code snippet provided by tenants is bootstrapped as a stand-alone Lambda function, with strong Firecracker-based isolation across different functions and execution environments addressing Launchpad’s requirements. This isolation provides dedicated resources, customizable access permissions, independent monitoring and operations, and automatic scaling for each function, while maintaining complete separation from other functions and their execution environments, as illustrated in the following diagram.

With Lambda being a serverless compute service, adopting it for the Launchpad architecture yielded several significant benefits. The major business benefit was that tenants could implement thousands of custom workflow augmentations on their own simply by providing code snippets, instead of the Launchpad engineering team being responsible for implementing them in the core platform code. Other benefits included:

  • Managed runtimes – AWS handles patching and updating the underlying infrastructure, operating system, and runtimes for customers, reducing the potential attack surface.
  • Fine-grained permissions – Each function can have its own set of access policies to tightly control what resources and actions it can access.
  • No need to pre-provision and pay for overprovisioned capacity – Lambda functions scale up and down automatically based on traffic patterns.
  • Built-in monitoring – Lambda functions emit detailed metrics, logs, and traces through Amazon CloudWatch and AWS X-Ray out of the box, making it straightforward to monitor tenant code execution.

To further reduce risks, Launchpad runs these Lambda functions with untrusted code in a dedicated AWS account. This account is separated from the core SaaS platform account. When end-users create a new function in the Launchpad authoring portal, they upload their code and specify the code handler to be executed during the invocation. Users can also map function input and output to Launchpad fields for further processing to enable an even higher degree of customizability and integration. The multi-tenant authoring service is a Control Plane component that runs as a microservice on the Amazon Elastic Kubernetes Service (Amazon EKS) cluster and uses the Lambda API for function lifecycle management, as illustrated in the following diagram. After a function resource is created, it can be used for further invocations.

Runtime architecture

At runtime, when Launchpad needs to invoke a function, it calls the Lambda Invoke API. Before the function is invoked, the multi-tenant runtime service performs a tenancy check to make sure the request is coming from an authorized tenant by doing the token validation. After a successful validation, the service invokes the required Lambda function. To invoke functions hosted in a different AWS account, the multi-tenant runtime service uses an AWS Identity and Access Management (IAM) role to assume the required permissions and invokes the Lambda service using the AWS SDK. The sequence of interactions is shown in the following architecture diagram.

The workflow consists of the following steps:

  1. An incoming user request reaches the application gateway service.
  2. The application gateway authenticates the request using the tenancy security service.
  3. After it’s authenticated, the request is forwarded to the multi-tenant runtime service
  4. The multi-tenant runtime service validates the supplied token and performs a tenancy check. This makes sure tenants can only invoke own functions they have permissions for (for example, functions they own).
  5. The multi-tenant runtime service pod assumes the IAM role required for invoking the tenant-specific Lambda function in a different AWS account.
  6. The multi-tenant runtime service pod invokes the required Lambda function.

Invoking the platform API from custom code is as straightforward as connecting to any external API. The custom code can authenticate with the platform using OAuth2. To facilitate the authentication, the developer can pass along the credentials as input parameters to the function from the core platform. Then the developer can create a corresponding record (isolated by tenant) in the platform that stores the credentials per function, and pass credentials as input parameters during invocation.

Distributed architecture observability

Operating a distributed architecture that runs untrusted code across multiple AWS accounts requires a comprehensive observability strategy. Launchpad’s approach combines centralized logging and monitoring with cross-account aggregation to provide a unified operational view of the platform.

The monitoring architecture uses CloudWatch Metrics to observe the Lambda functions, aggregating them through a centralized observability layer. This setup empowers platform operators to correlate Lambda function metrics with the core platform services running on Amazon EKS. Launchpad also collects per-function telemetry like function invocations, error rates, and execution time, which allows them to observe per-tenant metrics. These telemetry dimensions enable both a platform-wide and tenant-specific monitoring perspective.

For logging and troubleshooting, Launchpad implements a unified logging pipeline that aggregates Lambda function logs with application gateway and runtime service logs. Each request flowing through the system carries a correlation ID, so operators can trace execution paths across the core SaaS services and into the tenant functions running in the AWS account running tenant Lambda functions.

With this multi-layer observability architecture, Launchpad can maintain operational excellence while running tenant code securely at scale. Regular operational reviews drive continuous improvements in monitoring coverage and incident response procedures. Having per-tenant Lambda functions make it possible for Launchpad to use tenant-specific cost allocation tags, further empowering them to understand the cost footprint of running tenant custom code.

Best practices

When building a SaaS solution, maintaining a unified core code base is essential for scalability and manageability. Implementing per-tenant variations within the core platform code can lead to maintenance complexity and technical debt. Instead, architect your SaaS solution to have extension points, which allow your tenants to inject their custom code at specific points in the workflow, enabling customization without compromising the platform’s maintainability. This pattern makes sure the core SaaS platform remains clean and standardized while offering the flexibility that customers demand.

Additional best practices include:

  • Use separate accounts for running Lambda functions with untrusted tenant-provided code to make sure it’s isolated from your core SaaS platform code.
  • Grant absolute minimum required access permissions to the execution role assigned to the function. The custom code running within the execution environment gets permissions defined in the execution role when making requests to AWS API endpoints. If the function doesn’t need to reach out to AWS API endpoints, remove all permissions from the execution role and add an explicit AWSDenyAll policy.
  • Use separate Lambda functions for each code snippet and each tenant. This will provide the highest degree of cross-tenant isolation. Resources are not reused across different functions and execution environments.
  • Use Lambda layers in case you need to add a layer of vendor-provided code in order to keep it separated from the untrusted tenant-provided code.
  • Implement additional security controls, such as using Amazon Virtual Private Cloud (Amazon VPC) constructs to restrict network access and VPC Flow Logs for network activity monitoring.

Conclusion

The implementation of a secure untrusted code execution environment within SaaS platforms addresses a critical need for tenant customization while maintaining architectural integrity. Lambda offers a built-in isolation model, fine-grained security controls, and serverless scalability, so SaaS providers such as Launchpad can address the requirements of executing tenant-provided code in a multi-tenant environment and offer robust customization capabilities while maintaining strict security boundaries and operational efficiency. This architectural pattern enables providers to focus on core platform development while confidently supporting tenant-specific workflows through the secure and scalable Lambda execution environment.

To learn more, refer to the Security Overview of AWS Lambda white paper. For additional serverless architectural patterns, see Serverlessland.com.


About the authors

PackScan: Building real-time sort center analytics with AWS Services

Post Syndicated from Sairam Vangapally original https://aws.amazon.com/blogs/big-data/packscan-building-real-time-sort-center-analytics-with-aws-services/

Amazon manages a complex logistics network with multiple touch points, from fulfillment centers to sort centers to final customer delivery. Among these, sort centers play a crucial role in the middle mile, providing faster and more efficient package movement. Within Amazon’s Middle Mile operations, high-volume sort centers process millions of packages daily, making immediate access to operational data essential for optimizing efficiency and decision-making. Real-time visibility into key metrics—such as package movements, container statuses, and associate productivity—is critical for smooth logistics operations. To address the need for real-time operational planning, the Amazon Middle Mile team developed PackScan, a cloud-based platform designed to provide instant insights across the network. By significantly reducing data latency, PackScan enables proactive decision-making, so teams can monitor inbound package flows, optimize outbound shipments based on live data, track associate productivity, identify bottlenecks, and enhance overall operational efficiency—all in real time.

In this post, we explore how PackScan uses Amazon cloud-based services to drive real-time visibility, improve logistics efficiency, and support the seamless movement of packages across Amazon’s Middle Mile network.

Prerequisites

This post assumes a foundational understanding of the following services and concepts:

Although hands-on experience is not required, a conceptual understanding of these services will help in understanding the architecture, design patterns, and components discussed throughout the article.

Business challenges

Amazon’s sort centers handle over 15 million packages daily across more than 120 facilities in North America. Given this scale, even minor delays in operational insights can lead to inefficiencies, increased costs, and escalations. Traditionally, data latencies of up to an hour have restricted the ability to make proactive decisions, directly affecting productivity, resource allocation, and responsiveness—especially during peak periods like holiday seasons and big deal days.

Without immediate visibility into package movements, container statuses, and associate performance, operational teams face challenges in identifying and resolving bottlenecks in real time. The lack of timely insights can disrupt the flow of packages, leading to shipment delays, reduced throughput, and suboptimal facility performance. Addressing these inefficiencies required a solution capable of delivering real-time, high-fidelity data to support rapid decision-making.

To bridge this gap, Amazon’s Middle Mile organization needed a scalable platform that could enhance visibility, minimize latency, and provide up-to-the-minute insights into logistics operations. PackScan was designed to meet these demands, giving teams access to the real-time data necessary to optimize workflows, mitigate bottlenecks, and improve overall efficiency.

Data flow

In 2024, PackScan was deployed across 80 sort centers in the USA, enabling real-time package analytics. The solution powers Grafana dashboards, which refresh every 10 seconds by fetching live package data from OpenSearch Service. With this near real-time visibility, operations teams can monitor package movement and sorting efficiency across sort centers. The following diagram outlines how package scan data is ingested, processed, and made actionable.

Each sort center is equipped with hardware at inbound stations where packages arrive from trailers. Integrated barcode scanners automatically scan each package as it enters the sorting process. Every scan generates an SNS event, capturing key attributes such as the package ID, dimensions, the associate who performed the scan, and the timestamp and location of the scan.

After they’re generated, these SNS events are ingested into Data Firehose through a Lambda function, where the data undergoes real-time enrichment. During this process, additional attributes are appended, including the business logic rules. The enriched data is then streamed into OpenSearch Service, where events are indexed to enable fast and efficient querying. With the indexed package scan events available in OpenSearch Service, real-time analytics and monitoring become possible. The Grafana dashboards query this data every 10 seconds, providing operational insights into package inflow metrics and associate performance.

Solution overview

PackScan was implemented using a structured and scalable approach, using AWS cloud-based services to enable high-frequency data ingestion, real-time processing, and actionable insights. The architecture is designed to minimize latency while providing reliability, scalability, and operational efficiency. The solution is built around a serverless, event-driven architecture that dynamically scales based on data ingestion volumes. The architecture—illustrated in the following figure—enabled us to build a real-time data solution, utilizing the advantages of various AWS services to provide low-latency analytics, high scalability, and real-time operational insights across Amazon’s sort centers.

The following are the key components and features of the solution:

  • Real-time data processing – Lambda functions serve as the processing backbone of the system, handling 500,000 scan events per second. Each incoming event is processed by applying data transformations, enrichment, and validation before passing it downstream.
  • High-frequency data ingestion and streaming – Data Firehose is the primary ingestion pipeline, handling millions of scan events daily from thousands of barcode scanners across multiple sort centers. The Firehose streams handle incoming data of 12,000 PUT requests per second, maintaining smooth ingestion and low-latency streaming. Data retention policies are set to buffer and forward enriched events every 60 seconds or upon reaching 5 MB batch size, optimizing storage and processing efficiency.
  • Optimized querying and operational insights – OpenSearch Service is used to index and store the processed scan events, providing real-time querying and anomaly detection. The OpenSearch cluster consists of 12 data nodes (r5.4xlarge.search) and 3 primary nodes (r5.large.search), processing up to 10 GB of data per day with a rolling index strategy, where indexes are rotated every 24 hours to maintain query performance. The system supports concurrent queries per second, enabling logistics teams to perform rapid lookups and gain instant visibility into package movements.
  • Live visualization and dashboarding – Grafana, hosted on an m5.12xlarge EC2 instance, provides real-time visualization of key logistics metrics. The dashboards refresh every 10 seconds, querying OpenSearch and displaying up-to-the-minute package analytics. The setup includes multiple preconfigured dashboards, monitoring package flow at different inbound stations, and workforce efficiency. These dashboards support concurrent users, enabling supervisors and associates to track and optimize operations proactively. The following screenshot shows one of the real-time dashboards, with details of package flow by different routes within sort centers.

The entire PackScan architecture is designed for automatic scaling, adjusting dynamically based on data ingestion volume to maintain efficiency during peak and off-peak operations. This approach provides cost-effective resource utilization while maintaining high availability and performance.

Business outcomes

The implementation of PackScan has led to measurable improvements in operational efficiency, workforce productivity, and real-time decision-making across Amazon’s sort centers. By reducing data latency and enabling real-time insights, PackScan has transformed logistics operations in meaningful ways:

  • Widespread deployment – PackScan was deployed across 80 sort centers, supporting approximately 1,000 display monitors that provide real-time operational insights.
  • Significant reduction in data latency – Data latency dropped from approximately 1 hour to less than 1 minute, allowing for real-time operational responsiveness and minimizing workflow disruptions.
  • Proactive operational management – With dynamic workload balancing and instant bottleneck identification, supervisors can now address issues as they arise, leading to smoother operations and fewer escalations.
  • Boost in workforce productivity – The real-time performance feedback has enhanced associate engagement, resulting in a 25% increase in throughput per hour and 12% reduction in labor hours.

Overall, PackScan has redefined real-time logistics visibility within Amazon’s Middle Mile operations, empowering operational teams with actionable insights, enhanced workforce efficiency, and a data-driven approach to package movement and sort center performance.

Lessons learned and best practices

The deployment and scaling of PackScan provided valuable insights into optimizing real-time logistics visibility. Several key lessons and best practices emerged from this implementation:

  • Cloud architecture drives efficiency – Adopting Amazon technologies provides seamless scalability, reduced operational overhead, and lower infrastructure costs, while maintaining high reliability. The following table shows an approximate breakdown of monthly service costs observed in production. This is an estimation based on current pricing; we recommend checking the respective AWS service pricing pages to generate the most up-to-date quote. This architecture demonstrates that with combination of provisioned and serverless design, production-ready solutions can be built and scaled at a fraction of the cost of traditional infrastructure.
AWS Service Description Estimated Monthly Cost
Amazon EC2 Three EC2 instances of type m5.12xlarge hosting Grafana $1,700
AWS Lambda Streams SNS events to Data Firehose $4,000
Amazon Data Firehose Real-time data delivery with 12,000 records streaming to OpenSearch Service $1,500
Amazon OpenSearch Service Indexing and querying package scan events $28,000
  • Real-time visibility is a game changer – Immediate access to operational data enhances agility, enabling teams to make timely, data-driven decisions that prevent bottlenecks and improve throughput.
  • Continuous monitoring enhances decision-making – Operational dashboards should evolve with business needs. Regular monitoring and updates provide accuracy, usability, and relevance in driving informed decision-making.

By applying these best practices, PackScan has set a foundation for scalable, real-time logistics management, making sure that Amazon’s Middle Mile operations remain proactive, efficient, and highly responsive to changing business demands.

Conclusion

PackScan has successfully transformed real-time operational visibility within Amazon’s sort centers, addressing critical challenges in data latency, workforce productivity, and logistics efficiency. By using AWS services, particularly Data Firehose for real-time data delivery and OpenSearch Service for analytics, PackScan has enabled proactive decision-making, streamlined operations, and enhanced throughput in high-volume sort environments. Looking ahead, future enhancements will focus on further elevating operational intelligence and scalability, including:

  • Integrating predictive analytics to anticipate workflow bottlenecks and optimize resource allocation
  • Scaling the solution across additional operational scenarios, providing greater resilience and adaptability to dynamic logistics environments

With these advancements, PackScan will continue to drive operational excellence, cost-efficiency, and real-time decision-making capabilities, reinforcing Amazon’s commitment to innovation in logistics and supply chain management.

For those interested in implementing similar solutions, we recommend exploring AWS Serverless Architecture Patterns and the AWS Architecture Blog for additional insights and best practices in building scalable, real-time analytics solutions.


About the authors

Sairam Vangapally is a Data Engineer at Amazon with extensive experience architecting real-time, large-scale data platforms that power critical logistics operations across North America. He has led the design and deployment of end-to-end data pipelines, enabling high-throughput ingestion, transformation, and analytics at scale. He is passionate about building resilient data infrastructure and driving cross-functional collaboration to deliver solutions that accelerate operational insights and business impact.

Nitin Goyal serves as a Data Engineering Manager in Amazon’s Sort Center organization, where he leads initiatives to optimize operational efficiency across North American facilities. With over nine years of tenure at Amazon spanning multiple teams, he specializes in architecting high-performance data systems, with particular emphasis on real-time streaming pipelines, artificial intelligence, and low-latency solutions. His expertise drives the development of sophisticated operational workflows that enhance sort center productivity and effectiveness.

Enhance AI-assisted development with Amazon ECS, Amazon EKS and AWS Serverless MCP server

Post Syndicated from Elizabeth Fuentes original https://aws.amazon.com/blogs/aws/enhance-ai-assisted-development-with-amazon-ecs-amazon-eks-and-aws-serverless-mcp-server/

Today, we’re introducing specialized Model Context Protocol (MCP) servers for Amazon Elastic Container Service (Amazon ECS), Amazon Elastic Kubernetes Service (Amazon EKS), and AWS Serverless, now available in the AWS Labs GitHub repository. These open source solutions extend AI development assistants capabilities with real-time, contextual responses that go beyond their pre-trained knowledge. While Large Language Models (LLM) within AI assistants rely on public documentation, MCP servers deliver current context and service-specific guidance to help you prevent common deployment errors and provide more accurate service interactions.

You can use these open source solutions to develop applications faster, using up-to-date knowledge of Amazon Web Services (AWS) capabilities and configurations during the build and deployment process. Whether you’re writing code in your integrated development environment (IDE), or debugging production issues, these MCP servers support AI code assistants with deep understanding of Amazon ECS, Amazon EKS, and AWS Serverless capabilities, accelerating the journey from code to production. They work with popular AI-enabled IDEs, including Amazon Q Developer on the command line (CLI), to help you build and deploy applications using natural language commands.

  • The Amazon ECS MCP Server containerizes and deploys applications to Amazon ECS within minutes by configuring all relevant AWS resources, including load balancers, networking, auto-scaling, monitoring, Amazon ECS task definitions, and services. Using natural language instructions, you can manage cluster operations, implement auto-scaling strategies, and use real-time troubleshooting capabilities to identify and resolve deployment issues quickly.
  • For Kubernetes environments, the Amazon EKS MCP Server provides AI assistants with up-to-date, contextual information about your specific EKS environment. It offers access to the latest EKS features, knowledge base, and cluster state information. This gives AI code assistants more accurate, tailored guidance throughout the application lifecycle, from initial setup to production deployment.
  • The AWS Serverless MCP Server enhances the serverless development experience by providing AI coding assistants with comprehensive knowledge of serverless patterns, best practices, and AWS services. Using AWS Serverless Application Model Command Line Interface (AWS SAM CLI) integration, you can handle events and deploy infrastructure while implementing proven architectural patterns. This integration streamlines function lifecycles, service integrations, and operational requirements throughout your application development process. The server also provides contextual guidance for infrastructure as code decisions, AWS Lambda specific best practices, and event schemas for AWS Lambda event source mappings.

Let’s see it in action
If this is your first time using AWS MCP servers, visit the Installation and Setup guide in the AWS Labs GitHub repository to installation instructions. Once installed, add the following MCP server configuration to your local setup:

Install Amazon Q for command line and add the configuration to ~/.aws/amazonq/mcp.json. If you’re already an Amazon Q CLI user, add only the configuration.

{
  "mcpServers": {
    "awslabs.aws-serverless-mcp":  {
      "command": "uvx",
      "timeout": 60,
      "args": ["awslabs.aws_serverless_mcp_server@latest"],
    },
    "awslabs.ecs-mcp-server": {
      "disabled": false,
      "command": "uv",
      "timeout": 60,
      "args": ["awslabs.ecs-mcp-server@latest"],
    },
    "awslabs.eks-mcp-server": {
      "disabled": false,
      "timeout": 60,
      "command": "uv",
      "args": ["awslabs.eks-mcp-server@latest"],
    }
  }
}

For this demo I’m going to use the Amazon Q CLI to create an application that understands video using 02_using_converse_api.ipynb from Amazon Nova model cookbook repository as sample code. To do this, I send the following prompt:

I want to create a backend application that automatically extracts metadata and understands the content of images and videos uploaded to an S3 bucket and stores that information in a database. I'd like to use a serverless system for processing. Could you generate everything I need, including the code and commands or steps to set up the necessary infrastructure, for it to work from start to finish? - Use 02_using_converse_api.ipynb as example code for the image and video understanding.

Amazon Q CLI identifies the necessary tools, including the MCP serverawslabs.aws-serverless-mcp-server. Through a single interaction, the AWS Serverless MCP server determines all requirements and best practices for building a robust architecture.

I ask to Amazon Q CLI that build and test the application, but encountered an error. Amazon Q CLI quickly resolved the issue using available tools. I verified success by checking the record created in the Amazon DynamoDB table and testing the application with the dog2.jpeg file.

To enhance video processing capabilities, I decided to migrate my media analysis application to a containerized architecture. I used this prompt:

I'd like you to create a simple application like the media analysis one, but instead of being serverless, it should be containerized. Please help me build it in a new CDK stack.

Amazon Q Developer begins building the application. I took advantage of this time to grab a coffee. When I returned to my desk, coffee in hand, I was pleasantly surprised to find the application ready. To ensure everything was up to current standards, I simply asked:

please review the code and all app using the awslabsecs_mcp_server tools 

Amazon Q Developer CLI gives me a summary with all the improvements and a conclusion.

I ask it to make all the necessary changes, once ready I ask Amazon Q developer CLI to deploy it in my account, all using natural language.

After a few minutes, I review that I have a complete containerized application from the S3 bucket to all the necessary networking.

I ask Amazon Q developer CLI to test the app send it the-sea.mp4 video file and received a timed out error, so Amazon Q CLI decides to use the fetch_task_logs from awslabsecs_mcp_server tool to review the logs, identify the error and then fix it.

After a new deployment, I try it again, and the application successfully processed the video file

I can see the records in my Amazon DynamoDB table.

To test the Amazon EKS MCP server, I have code for a web app in the auction-website-main folder and I want to build a web robust app, for that I asked Amazon Q CLI to help me with this prompt:

Create a web application using the existing code in the auction-website-main folder. This application will grow, so I would like to create it in a new EKS cluster

Once the Docker file is created, Amazon Q CLI identifies generate_app_manifests from awslabseks_mcp_server as a reliable tool to create a Kubernetes manifests for the application.

Then create a new EKS cluster using the manage_eks_staks tool.

Once the app is ready, the Amazon Q CLI deploys it and gives me a summary of what it created.

I can see the cluster status in the console.

After a few minutes and resolving a couple of issues using the search_eks_troubleshoot_guide tool the application is ready to use.

Now I have a Kitties marketplace web app, deployed on Amazon EKS using only natural language commands through Amazon Q CLI.

Get started today
Visit the AWS Labs GitHub repository to start using these AWS MCP servers and enhance your AI-powered developmen there. The repository includes implementation guides, example configurations, and additional specialized servers to run AWS Lambda function, which transforms your existing AWS Lambda functions into AI-accessible tools without code modifications, and Amazon Bedrock Knowledge Bases Retrieval MCP server, which provides seamless access to your Amazon Bedrock knowledge bases. Other AWS specialized servers in the repository include documentation, example configurations, and implementation guides to begin building applications with greater speed and reliability.

To learn more about MCP Servers for AWS Serverless and Containers and how they can transform your AI-assisted application development, visit the Introducing AWS Serverless MCP Server: AI-powered development for modern applications, Automating AI-assisted container deployments with the Amazon ECS MCP Server, and Accelerating application development with the Amazon EKS MCP server deep-dive blogs.

— Eli

Modernizing applications with AWS AppSync Events

Post Syndicated from Ricardo Marques original https://aws.amazon.com/blogs/compute/modernizing-applications-with-aws-appsync-events/

In today’s fast-paced digital world, organizations are facing challenges for modernizing their applications. A common problem is the smooth shift from synchronous to asynchronous communication without substantial client or frontend alterations. When modernizing applications, it is often necessary to move from a synchronous communication model to an asynchronous one. However, this transition can be complex, especially when the client or frontend communicates synchronously. Adapting the current code for asynchronous communication demands significant time and resources.

AWS AppSync Events helps address this challenge by enabling you to build event-driven APIs that can bridge between synchronous and asynchronous communication models. With AppSync Events, you can modernize your backend architecture to leverage asynchronous patterns while maintaining compatibility with existing synchronous clients.

Overview

The solution comprises an API that converts client synchronous requests to asynchronous backend requests using AppSync Events.

For demonstrating the integration between the API and the backend, I’m simulating the backend processing using an asynchronous AWS Step Functions workflow. This workflow receives a Name and Surname event, waits 10 seconds, and posts a full-name event to the AppSync Event channel. To receive event notifications, the API subscribes to the AppSync channel. At the same time, the backend handles events asynchronously.

Figure 1: Representation of an API integrating a synchronous frontend with an asynchronous backend using AWS AppSync Events.

Figure 1: Representation of an API integrating a synchronous frontend with an asynchronous backend using AWS AppSync Events.

  1. The Amazon API Gateway makes a synchronous request to AWS Lambda and waits for the response.
  2. Lambda function starts the execution of the asynchronous workflow.
  3. After starting the workflow execution, Lambda connects to AppSync and creates a channel to receive asynchronous notifications (channels are ephemeral and unlimited. Here it creates one channel per request using the workflow execution ID).
  4. The workflow executes asynchronously, calling other workflows.
  5. Upon completion of the main workflow, it sends a POST request to the AppSync events API with the processing result. The POST is made to the channel that was created by the Lambda function using the workflow execution ID.
  6. AppSync receives the POST request and sends a notification to the subscriber, which in this case is the Lambda function. The entire process must be finished within the Lambda functions’s timeout limit you defined.
  7. Lambda sends the response to the API Gateway, which has been waiting for the synchronous response.

To better understand the Event API WebSocket Protocol used in this solution, refer to this AppSync documentation.

You can access the GitHub repo through this link: AppSync_Sync_Async_Integration.

The repository includes a comprehensive README file that walks you through the process of setting up and configuring the preceding solution.

Prerequisites

To follow this walkthrough, you need the following prerequisites:

With the full code, including API Gateway and Step Functions, on GitHub, this post only covers the core components: the AppSync Events API and the Lambda function.

Walkthrough

The following steps walk you through this solution.

Creating an AppSync event API with API Key Authorization

An AppSync Event API allows calls using API key, Amazon Cognito user pools, Lambda authorizer, OIDC, or AWS identity and Access Management (IAM). This solution uses API Key.

The infrastructure as code (IaC) has been created using Terraform. However, as of writing this post, there weren’t Terraform AppSync Event API resource available. Therefore, the AppSync Event API resources were made with AWS CloudFormation, which is imported and implemented by Terraform.

In the resource AWS:AppSync:Api, define the API name and Auth method:

Resources:
  #Creating the AppSync Events API
  EventAPI:
    Type: AWS::AppSync::Api
    Properties:
      Name: SyncAsyncAPI
      EventConfig:
        AuthProviders:
          - AuthType: API_KEY
        ConnectionAuthModes:
          - AuthType: API_KEY
        DefaultPublishAuthModes:
          - AuthType: API_KEY
        DefaultSubscribeAuthModes:
          - AuthType: API_KEY
#Creating the Events API Namespace
  DefaultNamespace:
    Type: AWS::AppSync::ChannelNamespace
    Properties:
      Name: AsyncEvents
      ApiId: !GetAtt EventAPI.ApiId
  
  #Creating the Events API APIKey
  EventAPIKey:
    Type: AWS::AppSync::ApiKey
    Properties:
      ApiId: !GetAtt EventAPI.ApiId
      Expires: 1748950672
      Description: 'API Key for Event API'

  #Creating the SecretsManager to store the APIKey
  SecretsManagerAPIKey:
    Type: AWS::SecretsManager::Secret
    Properties:
      Name: 'AppSyncEventAPIKEY'
      SecretString: !GetAtt EventAPIKey.ApiKey

To have the Host DNS, Realtime Endpoint, and Secret Manager created referenced by the Terraform template, output them:

Outputs:
  ApiARN:
    Description: 'The ARN ID'
    Value: !GetAtt EventAPI.ApiArn

  AppSyncHost:
    Description: 'The API Endpoint'
    Value: !GetAtt EventAPI.Dns.Http

  AppSyncRealTimeEndpoint:
    Description: 'The Real-time Endpoint'
    Value: !GetAtt EventAPI.Dns.Realtime

  SecretsManagerARN:
    Description: 'The ARN of the Secrets Manager entry'
    Value: !Ref SecretsManagerAPIKey

The key information needed from the AppSync Event API is:

  1. Host DNS: This DNS is used to send events to the API Channel through HTTP Post requests.
  2. Realtime endpoint: This endpoint is a WebSocket endpoint where the Lambda function connects to receive the events posted in the AppSync Channel.
  3. API Key: This key is used not only in the Post HTTP requests, but also to connect and subscribe to the AppSync channel.

Lambda Sync/Async API

In this solution, the Lambda function runs two tasks:

  1. Start an asynchronous workflow
  2. Subscribe to an event channel through WebSocket

To handle the WebSocket connection, use the websocket-client lib, which is a powerful Python lib developed for working with WebSockets.

Request isolation is maintained by using the same UUID for workflow name and AppSync channel name.

try:
        handler = WebSocketHandler()
        sfn_response = wf.start_workflow_async(event["body"])
        
        if sfn_response["status"] == "started":
            handler.execution_name = sfn_response["id"]
            handler.start_websocket_connection()
            
            return {
                'statusCode': 200,
                'body': json.dumps({ 
                        "id": handler.execution_name,
                        "nome completo": handler.final_name
                        })
            }
        else:
            raise ValueError("Workflow failed to start")

First, to initialize the WebSocket Connection, the subprotocols must be defined:

  • WEBSOCKET_PROTOCOL
  • Headers:
    • Host: The AppSync Host DNS (even with a WebSocket Connection, the HTTP Host must be sent)
    • x-api-key: The API key create fot the Event API.
    • Sec-Websocket-Protocol: WEBSOCKET_PROTOCOL
def start_websocket_connection(self) -> None:
        try: 
            """Initialize and start WebSocket connection."""
            header_str = self._create_connection_header()
            
            self.ws = websocket.WebSocketApp(
                os.environ["API_URL"],
                subprotocols=[WEBSOCKET_PROTOCOL, f'header-{header_str}'],
                on_open=self.on_open,
                on_message=self.on_message,
                on_error=self.on_error,
                on_close=self.on_close
)
            self.ws.run_forever()
        except Exception as e:
            return e
def _create_connection_header(self) -> str:
        """Create and encode connection header."""
        connection_header = {
            "host": os.environ["API_HOST"],
            "x-api-key": APIKEY,
            "Sec-WebSocket-Protocol": WEBSOCKET_PROTOCOL
        }
        return base64.b64encode(json.dumps(connection_header).encode()).decode()

Once the WebSocket connection is established, a first message with the type CONNECTION_INIT_TYPE must be sent.

To subscribe to the channel by which our function is notified when the Step Functions workflow finishes, send a second message with the type SUBSCRIBE_TYPE, an ID, the channel name and authorization.

For more information about types of message, read this AppSync documentation.

def on_open(self, ws: websocket.WebSocketApp) -> None:
        try:
            """Handle WebSocket connection opening and send initial messages."""
            logger.info("Connection opened")
            
            # Send connection initialization
            connection_init = {"type": CONNECTION_INIT_TYPE}
            ws.send(json.dumps(connection_init))

            # Send subscription
            subscription_msg = {
                "type": SUBSCRIBE_TYPE,
                "id": self.execution_name,
                "channel": f"{os.environ["APPSYNC_NAMESPACE"]}/{self.execution_name}",
                "authorization": {
                    "x-api-key": APIKEY,
                    "host": os.environ["API_HOST"]
                }
            }
            
            logger.info("Sending subscription")
            ws.send(json.dumps(subscription_msg))
        except Exception as e:
            self.on_error = e

After receiving the message confirming the subscription, wait for messages with the type data. Whenever a message with this type arrives, execute the logic to identify if the workflow was successfully executed, and then close the connection.

def on_message(self, ws: websocket.WebSocketApp, message: str) -> None:
        """Handle incoming WebSocket messages."""
        logger.info("Message received: %s", message)
        try:
            message_dict = json.loads(message)
            required_keys = ["id", "type", "event"]
            
            if all(key in message_dict for key in required_keys):
                event_json = json.loads(message_dict["event"])
                
                if (message_dict["id"] == self.execution_name and 
                    message_dict["type"] == "data"):
                    
                    self.final_name = event_json["nome_completo"]
                    logger.info("Message received: %s", self.final_name)
                    logger.info("Successfully received return message")
                    logger.info("Ending processing")
                    
                    self.message_queue = {
                        "status": SUCCESS_STATUS,
                        "executionID": message_dict["id"]
                    }
                    ws.close()
        except json.JSONDecodeError as e:
            logger.error("Failed to parse message: %s", str(e))
        except Exception as e:
            logger.error("Error processing message: %s", str(e))

Conclusion

In this post, you learned how to use event-driven architectures and the capabilities of AWS AppSync Events to integrate synchronous and asynchronous communication patterns in your applications. This allows you to modernize your systems without the need for extensive modifications to your existing frontend codebase. Explore the demonstrations and documentation provided in the GitHub repository to gain a deeper understanding of how AppSync Events can be applied to your specific use cases.

To learn more about serverless architectures and asynchronous invocation patterns, see Serverless Land.

Enhancing multi-account activity monitoring with event-driven architectures

Post Syndicated from Anton Aleksandrov original https://aws.amazon.com/blogs/compute/enhancing-multi-account-activity-monitoring-with-event-driven-architectures/

Enterprise cloud environments are growing increasingly complex as they scale, with organizations managing hundreds to thousands of Amazon Web Services (AWS) accounts across multiple business units and AWS Regions. Organizations need efficient ways to collect, transport, and analyze activity data for threat detection and compliance monitoring. This presents unique challenges for enterprise Application Security (AppSec) teams, cloud security vendors, and DevSecOps professionals, because traditional polling-based monitoring approaches struggle to provide real-time activity insights needed for modern cloud operations.

In this post, you will learn to use AWS CloudTrail and Amazon EventBridge for real-time cloud activity monitoring and automated response.

Overview

As organizations expand their cloud footprint, account activity monitoring that comprehensively tracks user actions and successfully identifies security threats becomes crucial for threat detection and compliance. Although AWS provides native tools—such as CloudTrail for API activity capture, EventBridge for real-time event routing, AWS Organizations for multi-account management, and AWS Config for resource evaluation—many enterprises struggle with the volume of activities while maintaining efficiency and controlling costs. Organizations need to carefully architect solutions to effectively use these tools as their environments scale.

Traditional polling-based techniques, which worked well for smaller environments, can become unsustainable when scaled to enterprise deployments, where the volume of activity data grows exponentially with each new account and service. API polling limitations, growing data volumes, and increasing demand for real-time analysis are pushing teams to rethink their architectural approach.

Figure 1. Poll model, periodically retrieving the latest state.

Adopting push-based event-driven architectures offers a compelling solution for AppSec teams and cloud security vendors facing these challenges. Using AWS services, such as CloudTrail and EventBridge, allows these teams and vendors to build scalable activity monitoring solutions that overcome the limitations of traditional polling-based approaches and provide real-time notifications across thousands of AWS accounts. This approach not only enables security use cases but also supports broader real-time operational monitoring, compliance reporting, and automation requirements.

“By integrating AWS CloudTrail and Amazon EventBridge, we’ve built a scalable architecture to monitor activity across thousands of AWS accounts. This provides the visibility needed to detect threats in real time and protect large, distributed AWS environments.” — Rob Solomon, Senior Cloud Solution Architect, CrowdStrike

Solution components

Enterprise AppSec teams and cloud security vendors share common requirements when building multi-account monitoring solutions. They need to efficiently collect activity data across thousands of accounts, transport it to a centralized location for analysis, and process it in real-time to detect threats and compliance violations. The solution must scale seamlessly from dozens to thousands of accounts while remaining highly-performant and cost-efficient. At its core, a scalable multi-account activity monitoring solution consists of three components: activity data collection, cross-account transport to a centralized location, and processing. In the following sections, you will learn how AppSec teams and cloud security vendors can implement each step efficiently while avoiding common pitfalls.

Figure 2. Push model. Account activity is collected at the source, and pushed to the AppSec or cloud security vendor account for further processing.

Data collection strategies

Many teams begin their cloud activity monitoring journey by polling the resource status through service management APIs. Although this approach works good for retrieving the latest resource state on-demand, its fundamental limitation is inability to detect state changes efficiently, necessitating continuous querying of all resources at fixed intervals. Consider a scenario where you’re monitoring 1,000 accounts, with 100 resources in each account. A single polling cycle would necessitate 100,000 API requests, consuming over 28 million API calls daily if running at five-minute intervals. This inefficiency compounds as environments grow, leading to throttling issues, increased costs, and scaling challenges.

AWS Config improved upon this by offering continuous resource configuration tracking without manual polling. Although this works excellent for configuration compliance and a history of changes for auditing, AWS Config reports changes on a best-effort basis and is not optimal for real-time threat detection.

To overcome this constraint, your solution can use services such as CloudTrail and EventBridge as primary data sources, complemented by intelligent on-demand targeted API polling. CloudTrail records API activity across AWS services, providing a detailed history of actions taken by users, roles, and AWS services in your accounts. Over 250 AWS services automatically report their activity and API calls to CloudTrail and EventBridge in real-time. This allows you to capture this information, providing a detailed history of actions taken in your accounts, and enabling security analysis, resource state change tracking, and compliance audit.

Figure 3. Over 250 AWS services are automatically emitting activity events to CloudTrail.

When a resource state changes, commonly as a result of a management API call, the affected service sends an event to CloudTrail and EventBridge. Your monitoring solution can examine the event payload to determine if polling for supplementary data is necessary, particularly when the initial payload lacks complete information. This provides you with comprehensive service coverage with reduced maintenance effort. This hybrid approach guarantees delivery of activity data to eliminate monitoring blind spots, while significantly reducing AWS management API quota consumption.

Cross-account data transport

Your solution should transport activity data from thousands of tenant accounts into a small number of centralized accounts, such as a regional AppSec account, for further processing and analysis. The solution must be secure, scalable, resilient, and cost-efficient while maintaining real-time delivery.

The most direct way to achieve it is to enable Amazon S3 event notifications for new objects that are created in the CloudTrail trails S3 bucket. When you receive the notification, you can retrieve and process new activities.

Figure 4. Exporting CloudTrail events into an S3 bucket and retrieving after receiving a notification.

This direct way to consume CloudTrail events has one important consideration: typically it can take an average of five minutes to deliver events to Amazon S3. Teams and vendors looking for lower mean-time-to-detect (MTTD) and mean-time-to-respond (MTTR) should evaluate transporting CloudTrail events across accounts with EventBridge, which provides close-to-real-time delivery.

Transporting events with EventBridge

EventBridge is a serverless event router that connects applications. It receives events from various sources, such as CloudTrail, and routes them to multiple targets based on defined rules.

Using EventBridge for cross-account data transport comes with several major benefits:

There are two approaches you can take for delivering cross-account events with EventBridge: direct service-to-service or service-to-API-endpoint.

The first approach uses the EventBridge direct bus-to-bus and bus-to-service delivery capabilities. This method is most suitable when you want AWS to handle data ingestion on the receiving end. The delivery target is always either an EventBridge bus, or another AWS service, such as an Amazon Simple Queue Service (Amazon SQS) queue, Amazon Kinesis Data Streams stream, or an AWS Lambda function. With support for up to 18,750 target invocations per second and native AWS Identity and Access Management (IAM) integration, this method is particularly suitable for large multi-account deployments.

The second approach uses the EventBridge API destinations feature. This method is most suitable when you have existing HTTP-based ingestion endpoints in place. Although it offers lower throughput, it provides greater flexibility for ingestion endpoint and authentication methods implementation, making it attractive for AppSec teams and cloud security vendors integrating with existing ingestion infrastructure.

Figure 5. Emitting CloudTrail events in real-time through EventBridge.

The following table summarizes two approaches for transporting events across accounts with EventBridge.

Direct bus-to-bus or bus-to-service API destinations
Data ingestion implementation effort Minimal Needed
Default target invocations per second (TPS) quotas Up to 18,750 (region dependent) Up to 300 (region dependent)
Can the TPS quota be increased Yes Yes
Authorization support Native AWS IAM, fully handled by AWS Basic, OAuth2, API Key. You’re responsible for implementing credentials validation during ingestion.
Cross-account delivery costs $1 per million events $0.20 per million events

Go to the EventBridge quotas and pricing pages for more details.

Processing architecture

Processing would commonly be done by existing products and services the AppSec team or cloud security vendor provides for activity analysis. The architecture for event processing pipeline operating at enterprise scale must consider design decisions to handle large and potentially irregular event volumes while maintaining high performance, as shown in the following figure.

Figure 6. An activity event processing pipeline, with priority-based processing.

Use the following best practices for a robust processing architecture:

  • Buffer ingested events Use services such as Amazon SQS, Amazon Kinesis Data Streams, or Amazon Managed Streaming for Apache Kafka to buffer incoming events, handle traffic surges, and make sure of reliable processing.
  • Use serverless services that scale automatically, or invest in automated scaling mechanisms that adjust processing capacity based on event volume
  • Minimize polling: Resort to intelligent on-demand polling, only poll when you need additional data that is not available in the CloudTrail event payload.
  • Routing and classification: Rather than processing all events equally, implement intelligent classification and routing early in your pipeline. Security-related events such as IAM changes or security group modifications should take priority over routine activities or data events. This approach helps to control costs while maintaining rapid detection of important security events.
  • Cost optimization: At the enterprise scale, cost optimization becomes crucial. Use EventBridge rules in source accounts to filter out irrelevant events before they enter your processing pipeline. Consider implementing regional collection points to optimize data transfer costs. When using Lambda functions for data processing, use batch processing to reduce invocation costs. Evaluate which event types must be delivered in real-time through EventBridge, which event types can be delayed and collected through S3 bucket export, and which events should be discarded.
  • Observability: Monitor the ingestion and processing throughput to react to potential slowdowns early. Detect when source accounts are approaching EventBridge quotas. Consider using AWS Service Quotas to request quota increases automatically through APIs.
  • Cross-Region considerations: Design your architecture to support efficient cross-Region event collection while respecting data sovereignty requirements. Consider implementing regional processing nodes with centralized aggregation for global security analysis.
  • Integration patterns: Modern security solutions must integrate with existing security tools and workflows. Implement standardized output formats that allow seamless integration with SIEM systems, ticketing platforms, and automation frameworks. Consider publishing security findings back to EventBridge buses to enable automated remediation workflows. If you’re a cloud security vendor, then consider integrating with EventBridge as an SaaS partner.

Conclusion

Event-driven architectures present a powerful opportunity for building scalable multi-account activity monitoring solutions. Using services such as AWS CloudTrail and Amazon EventBridge allows teams to overcome the limitations of traditional polling-based approaches while achieving close to real-time delivery.The shift to event-driven security monitoring isn’t just an architectural choice—it’s becoming a necessity for teams operating at enterprise scale. This approach enables security teams to achieve the real-time threat detection capabilities needed in today’s cloud environments while maintaining operational efficiency and cost control.