Tag Archives: Amazon EventBridge

Use a reusable ETL framework in your AWS lake house architecture

Post Syndicated from Ashutosh Dubey original https://aws.amazon.com/blogs/architecture/use-a-reusable-etl-framework-in-your-aws-lake-house-architecture/

Data lakes and lake house architectures have become an integral part of a data platform for any organization. However, you may face multiple challenges while developing a lake house platform and integrating with various source systems. In this blog, we will address these challenges and show how our framework can help mitigate these issues.

Lake house architecture using AWS

Figure 1 shows a typical lake house implementation in an Amazon Web Services (AWS) environment.

Typical lake house implementation in AWS

Figure 1. Typical lake house implementation in AWS

In this diagram we have five layers. The number of layers and names can vary per environmental requirements, so check recommended data layers for more details.

  1. Landing layer. This is where all source files are dropped in their original format.
  2. Raw layer. This is where all source files are converted and stored in a common parquet format.
  3. Stage layer. This is where we maintain a history of dimensional tables as Slowly Changing Dimension Type 2 (SCD2). Apache Hudi is used for SCD2 in the Amazon Simple Storage Service (Amazon S3) bucket, and an AWS Glue job is used to write to Hudi tables. AWS Glue is used to perform any extract, transform, and load (ETL) job to move, cleanse, validate, or transform files between any two layers. For details, see using the Hudi framework in AWS Glue.
  4. Presentation layer. This is where data is being cleansed, validated, and transformed, using an AWS Glue job, in accordance with business requirements.
  5. Data warehouse layer. Amazon Redshift is being used as the data warehouse where the curated or cleansed data resides. We can either copy the data using an AWS Glue python shell job, or create a Spectrum table out of the Amazon S3 location.

The data lake house architecture shows two types of data ingestion patterns, push and pull. In the pull-based ingestion, services like AWS Glue or AWS Lambda are used to pull data from sources like databases, APIs, or flat files into the data lake. In the push-based pattern, third-party sources can directly upload files into a landing Amazon S3 bucket in the data lake. Amazon Managed Workflows for Apache Airflow (Amazon MWAA) is used to orchestrate data pipelines that move data from the source systems into a data warehouse. Amazon EventBridge is used to schedule the Airflow directed acyclic graph (DAG) data pipelines. Amazon RDS for PostgreSQL is used to store metadata for configuration of the data pipelines. A data lake architecture with these capabilities provides a scalable, reliable, and efficient solution for data pipelines.

Data pipeline challenges

Maintaining data pipelines in a large lake house environment can be quite challenging. There are a number of hurdles one faces regularly. Creating individual AWS Glue jobs for each task in every Airflow DAG can lead to hundreds of AWS Glue jobs to manage. Error handling and job restarting gets increasingly more complex as the number of pipelines grows. Developing a new data pipeline from scratch takes time, due to the boilerplate code involved. The production support team can find it challenging to monitor and support such a large number of data pipelines. Data platform monitoring becomes arduous at that scale. Ensuring overall maintainability, robustness, and governability of data pipelines in a lake house is a constant struggle.

The benefits of a data pipeline framework

Having a data pipeline framework can significantly reduce the effort required to build data pipelines. This framework should be able to create a lake house environment that is easy to maintain and manage. It should also increase the reusability of code across data pipelines. Effective error handling and recovery mechanisms in the framework should make the data pipelines robust. Support for various data ingestion patterns like batch, micro batch, and streaming should make the framework versatile. A framework with such capabilities will help you build scalable, reliable, and flexible data pipelines, with reduced time and effort.

Reusable ETL framework

In a metadata-driven reusable framework, we have pre-created templates for different purposes. Metadata tables are used to configure the data pipelines.

Figure 2 shows the architecture of this framework:

Reusable ETL framework architecture

Figure 2. Reusable ETL framework architecture

In this framework, there are pre-created AWS Glue templates for different purposes, like copying files from SFTP to landing bucket, fetching rows from a database, converting file formats in landing to parquet in the raw layer, writing to Hudi tables, copying parquet files to Redshift tables, and more.

These templates are stored in a template bucket, and details of all templates are maintained in a template config table with a template_id in Amazon Relational Database Service (Amazon RDS). Each data pipeline (Airflow DAG) is represented as a flow_id in the main job config table. Each flow_id can have one or more tasks, and each task refers to a template_id. This framework can support both the type of ingestions—pull-based (scheduled pipelines) and push-based (initiated pipelines). The following steps show the detailed flow of the pipeline in Figure 2.

  1. To schedule a pipeline, the “Scheduled DAG Invoker Lambda” is scheduled in EventBridge, with flow_id of the pipeline as the parameter.
  2. The source drops files in a landing bucket.
  3. An event is initiated and calls the “Triggered DAG Invoker” Lambda. This Lambda function gets the file name from the event to call the Airflow API.
  4. A Lambda function queries an RDS metadata table with the parameter to get the DAG name.
  5. Both of the Lambda functions call the Airflow API to start the DAG.
  6. The Airflow webserver locates the DAG from the S3 location and passes it to the executor.
  7. The DAG is initiated.
  8. The DAG calls the functions in the common util python script with all required parameters.
  9. For any pipeline, the util script gets all the task details from the metadata table, along with the AWS Glue template name and location.
  10. For any database or API connectivity, the util function gets the secret credentials from AWS Secrets Manager based on the secret_id.
  11. The AWS Glue template file from the S3 location starts the AWS Glue job using Boto3 API by passing the required parameters. Once the AWS Glue job completes successfully, it deletes the job.
  12. If the pipeline contains any Lambda calls, the util script calls the Lambda function as per the configuration parameter.
  13. If the AWS Glue job fails due to any error in Step #11, the script captures the error message and sends an Amazon Simple Notification Service (Amazon SNS) notification.

For developing any new pipeline, the developer must identify the number of tasks that need to be created for the DAG. Identify which template can be used for which task, and insert configuration entries to the metadata tables accordingly. If there is no template available, create a new template to reuse later. Finally, create the Airflow DAG script and place it in the DAG location.

Conclusion

The proposed framework leverages AWS native services to provide a scalable and cost-effective solution. It allows faster development due to reusable components. You can dynamically generate and delete AWS Glue jobs as needed. This framework enables jobs tracking by configuration tables, supports error handling, and provides email notification. You can create scheduled and event-driven data pipelines to ingest data from various sources in different formats. And you can tune the performance and cost of AWS Glue jobs, by updating configuration parameters without changing any code.

A reusable framework is a great practice for any development project, as it improves time to market and standardizes development patterns in a team. This framework can be used in any AWS data lake or lake house environments with any number of data layers. This makes pipeline development faster, and error handing and support easier. You can enhance and customize even further to have more features like data reconciliation, micro-batch pipelines, and more.

Further reading:

Monitor data pipelines in a serverless data lake

Post Syndicated from Virendhar Sivaraman original https://aws.amazon.com/blogs/big-data/monitor-data-pipelines-in-a-serverless-data-lake/

AWS serverless services, including but not limited to AWS Lambda, AWS Glue, AWS Fargate, Amazon EventBridge, Amazon Athena, Amazon Simple Notification Service (Amazon SNS), Amazon Simple Queue Service (Amazon SQS), and Amazon Simple Storage Service (Amazon S3), have become the building blocks for any serverless data lake, providing key mechanisms to ingest and transform data without fixed provisioning and the persistent need to patch the underlying servers. The combination of a data lake in a serverless paradigm brings significant cost and performance benefits. The advent of rapid adoption of serverless data lake architectures—with ever-growing datasets that need to be ingested from a variety of sources, followed by complex data transformation and machine learning (ML) pipelines—can present a challenge. Similarly, in a serverless paradigm, application logs in Amazon CloudWatch are sourced from a variety of participating services, and traversing the lineage across logs can also present challenges. To successfully manage a serverless data lake, you require mechanisms to perform the following actions:

  • Reinforce data accuracy with every data ingestion
  • Holistically measure and analyze ETL (extract, transform, and load) performance at the individual processing component level
  • Proactively capture log messages and notify failures as they occur in near-real time

In this post, we will walk you through a solution to efficiently track and analyze ETL jobs in a serverless data lake environment. By monitoring application logs, you can gain insights into job execution, troubleshoot issues promptly to ensure the overall health and reliability of data pipelines.

Overview of solution

The serverless monitoring solution focuses on achieving the following goals:

  • Capture state changes across all steps and tasks in the data lake
  • Measure service reliability across a data lake
  • Quickly notify operations of failures as they happen

To illustrate the solution, we create a serverless data lake with a monitoring solution. For simplicity, we create a serverless data lake with the following components:

  • Storage layer – Amazon S3 is the natural choice, in this case with the following buckets:
    • Landing – Where raw data is stored
    • Processed – Where transformed data is stored
  • Ingestion layer – For this post, we use Lambda and AWS Glue for data ingestion, with the following resources:
    • Lambda functions – Two Lambda functions that run to simulate a success state and failure state, respectively
    • AWS Glue crawlers – Two AWS Glue crawlers that run to simulate a success state and failure state, respectively
    • AWS Glue jobs – Two AWS Glue jobs that run to simulate a success state and failure state, respectively
  • Reporting layer – An Athena database to persist the tables created via the AWS Glue crawlers and AWS Glue jobs
  • Alerting layer – Slack is used to notify stakeholders

The serverless monitoring solution is devised to be loosely coupled as plug-and-play components that complement an existing data lake. The Lambda-based ETL tasks state changes are tracked using AWS Lambda Destinations. We have used an SNS topic for routing both success and failure states for the Lambda-based tasks. In the case of AWS Glue-based tasks, we have configured EventBridge rules to capture state changes. These event changes are also routed to the same SNS topic. For demonstration purposes, this post only provides state monitoring for Lambda and AWS Glue, but you can extend the solution to other AWS services.

The following figure illustrates the architecture of the solution.

The architecture contains the following components:

  • EventBridge rules – EventBridge rules that capture the state change for the ETL tasks—in this case AWS Glue tasks. This can be extended to other supported services as the data lake grows.
  • SNS topic – An SNS topic that serves to catch all state events from the data lake.
  • Lambda function – The Lambda function is the subscriber to the SNS topic. It’s responsible for analyzing the state of the task run to do the following:
    • Persist the status of the task run.
    • Notify any failures to a Slack channel.
  • Athena database – The database where the monitoring metrics are persisted for analysis.

Deploy the solution

The source code to implement this solution uses AWS Cloud Development Kit (AWS CDK) and is available on the GitHub repo monitor-serverless-datalake. This AWS CDK stack provisions required network components and the following:

  • Three S3 buckets (the bucket names are prefixed with the AWS account name and Regions, for example, the landing bucket is <aws-account-number>-<aws-region>-landing):
    • Landing
    • Processed
    • Monitor
  • Three Lambda functions:
    • datalake-monitoring-lambda
    • lambda-success
    • lambda-fail
  • Two AWS Glue crawlers:
    • glue-crawler-success
    • glue-crawler-fail
  • Two AWS Glue jobs:
    • glue-job-success
    • glue-job-fail
  • An SNS topic named datalake-monitor-sns
  • Three EventBridge rules:
    • glue-monitor-rule
    • event-rule-lambda-fail
    • event-rule-lambda-success
  • An AWS Secrets Manager secret named datalake-monitoring
  • Athena artifacts:
    • monitor database
    • monitor-table table

You can also follow the instructions in the GitHub repo to deploy the serverless monitoring solution. It takes about 10 minutes to deploy this solution.

Connect to a Slack channel

We still need a Slack channel to which the alerts are delivered. Complete the following steps:

  1. Set up a workflow automation to route messages to the Slack channel using webhooks.
  2. Note the webhook URL.

The following screenshot shows the field names to use.

The following is a sample message for the preceding template.

  1. On the Secrets Manager console, navigate to the datalake-monitoring secret.
  2. Add the webhook URL to the slack_webhook secret.

Load sample data

The next step is to load some sample data. Copy the sample data files to the landing bucket using the following command:

aws s3 cp --recursive s3://awsglue-datasets/examples/us-legislators s3://<AWS_ACCCOUNT>-<AWS_REGION>-landing/legislators

In the next sections, we show how Lambda functions, AWS Glue crawlers, and AWS Glue jobs work for data ingestion.

Test the Lambda functions

On the EventBridge console, enable the rules that trigger the lambda-success and lambda-fail functions every 5 minutes:

  • event-rule-lambda-fail
  • event-rule-lambda-success

After a few minutes, the failure events are relayed to the Slack channel. The following screenshot shows an example message.

Disable the rules after testing to avoid repeated messages.

Test the AWS Glue crawlers

On the AWS Glue console, navigate to the Crawlers page. Here you can start the following crawlers:

  • glue-crawler-success
  • glue-crawler-fail

In a minute, the glue-crawler-fail crawler’s status changes to Failed, which triggers a notification in Slack in near-real time.

Test the AWS Glue jobs

On the AWS Glue console, navigate to the Jobs page, where you can start the following jobs:

  • glue-job-success
  • glue-job-fail

In a few minutes, the glue-job-fail job status changes to Failed, which triggers a notification in Slack in near-real time.

Analyze the monitoring data

The monitoring metrics are persisted in Amazon S3 for analysis and can be used of historical analysis.

On the Athena console, navigate to the monitor database and run the following query to find the service that failed the most often:

SELECT service_type, count(*) as "fail_count"
FROM "monitor"."monitor"
WHERE event_type = 'failed'
group by service_type
order by fail_count desc;

Over time with rich observability data – time series based monitoring data analysis will yield interesting findings.

Clean up

The overall cost of the solution is less than one dollar but to avoid future costs, make sure to clean up the resources created as part of this post.

Summary

The post provided an overview of a serverless data lake monitoring solution that you can configure and deploy to integrate with enterprise serverless data lakes in just a few hours. With this solution, you can monitor a serverless data lake, send alerts in near-real time, and analyze performance metrics for all ETL tasks operating in the data lake. The design was intentionally kept simple to demonstrate the idea; you can further extend this solution with Athena and Amazon QuickSight to generate custom visuals and reporting. Check out the GitHub repo for a sample solution and further customize it for your monitoring needs.


About the Authors

Virendhar (Viru) Sivaraman is a strategic Senior Big Data & Analytics Architect with Amazon Web Services. He is passionate about building scalable big data and analytics solutions in the cloud. Besides work, he enjoys spending time with family, hiking & mountain biking.
Vivek Shrivastava is a Principal Data Architect, Data Lake in AWS Professional Services. He is a Bigdata enthusiast and holds 14 AWS Certifications. He is passionate about helping customers build scalable and high-performance data analytics solutions in the cloud. In his spare time, he loves reading and finds areas for home automation.

How Thomson Reuters monitors and tracks AWS Health alerts at scale

Post Syndicated from Srinivasa Shaik original https://aws.amazon.com/blogs/architecture/how-thomson-reuters-monitors-and-tracks-aws-health-alerts-at-scale/

Thomson Reuters Corporation is a leading provider of business information services. The company’s products include highly specialized information-enabled software and tools for legal, tax, accounting and compliance professionals combined with the world’s most trusted global news service: Reuters.

Thomson Reuters is committed to a cloud first strategy on AWS, with thousands of applications hosted on AWS that are critical to its customers, with a growing number of AWS accounts that are used by different business units to deploy the applications. Service Management in Thomson Reuters is a centralized team, who needs an efficient way to measure, monitor and track the health of AWS services across the AWS environment. AWS Health provides the required visibility to monitor the performance and availability of AWS services and scheduled changes or maintenance that may impact their applications.

With approximately 16,000 AWS Health events received in 2022 alone due to the scale at which Thomson Reuters is operating on AWS, manually tracking AWS Health events is challenging. This necessitates a solution to provide centralized visibility of Health alerts across the organization, and an efficient way to track and monitor the Health events across the AWS accounts. Thomson Reuters requires retaining AWS Health event history for a minimum of 2 years to derive indicators affecting performance and availability of applications in the AWS environment and thereby ensuring high service levels to customers. Thomson Reuters utilizes ServiceNow for tracking IT operations and Datadog for infrastructure monitoring which is integrated with AWS Health to measure and track all the events and estimate the health performance with key indicators. Before this solution, Thomson Reuters didn’t have an efficient way to track scheduled events, and no metrics to identify the applications impacted by these Health events.

In this post, we will discuss how Thomson Reuters has implemented a solution to track and monitor AWS Health events at scale, automate notifications, and efficiently track AWS scheduled changes. This gives Thomson Reuters visibility into the health of AWS resources using Health events, and allows them to take proactive measures to minimize impact to their applications hosted on AWS.

Solution overview

Thomson Reuters leverages AWS Organizations to centrally govern their AWS environment. AWS Organization helps to centrally manage accounts and resources, optimize the cost, and simplify billing. The AWS environment in Thomson Reuters has a dedicated organizational management account to create Organizational Units (OUs), and policies to manage the organization’s member accounts. Thomson Reuters enabled organizational view within AWS Health, which once activated provides an aggregated view of AWS Health events across all their accounts (Figure 1).

Architecture to track and monitor AWS Health events

Figure 1. Architecture to track and monitor AWS Health events

Let us walk through the architecture of this solution:

  1. Amazon CloudWatch Scheduler invokes AWS Lambda every 10 minutes to fetch AWS Health API data from the Organization Management account.
  2. Lambda leverages execution role permissions to connect to the AWS Health API and send events to Amazon EventBridge. The loosely coupled architecture of Amazon EventBridge allows for storing and routing of the events to various targets based upon the AWS Health Event Type category.
  3. AWS Health Event is matched against the EventBridge rules to identify the event category and route to the target AWS Lambda functions that process specific AWS Health Event types.
  4. The AWS Health events are routed to ServiceNow and Datadog based on the AWS Health Event Type category.
  5. If the Health Event Type category is “Scheduled change“ or ” Issues“ then it is routed to ServiceNow.
    • The event is stored in a DynamoDB table to track the AWS Health events beyond the 90 days history available in AWS Health.
    • If the entity value of the affected AWS resource exists inside the Health Event, then tags associated with that entity value are used to identify the application and resource owner to notify. One of the internal policies mandates the owners to include AWS resource tags for every AWS resource provisioned. The DynamoDB table is updated with additional details captured based on entity value.
    • Events that are not of interest are excluded from tracking.
    • A ServiceNow ticket is created containing the details of the AWS Health event and includes additional details regarding the application and resource owner that are captured in the DynamoDB table. The ServiceNow credentials to connect are stored securely in AWS Secrets Manager. The ServiceNow ticket details are also updated back in DynamoDB table to correlate AWS Health event with a ServiceNow tickets.
  6. If the Health Event Type category is “Account Notification”, then it is routed to Datadog.
    • All account notifications including public notifications are routed to Datadog for tracking.
    • Datadog monitors are created to help derive more meaningful information from the account notifications received from the AWS Health events.

AWS Health Event Type “Account Notification” provides information about the administration or security of AWS accounts and services. These events are mostly informative, but some of them need urgent action, and tracking each of these events within Thomson Reuters incident management is substantial. Thomson Reuters has decided to route these events to Datadog, which is monitored by the Global Command Center from the centralized Service Management team. All other AWS Health Event types are tracked using ServiceNow.

ServiceNow to track scheduled changes and issues

Thomson Reuters leverages ServiceNow for incident management and change management across the organization, including both AWS cloud and on-premises applications. This allows Thomson Reuters to continue using the existing proven process to track scheduled changes in AWS through the ServiceNow change management process and AWS Health issues and investigations by using ServiceNow incident management, notify relevant teams, and monitor until resolution. Any AWS service maintenance or issues reported through AWS Health are tracked in ServiceNow.

One of the challenges while processing thousands of AWS Health events every month is also to identify and track events that has the potential to cause significant impact to the applications. Thomson Reuters decided to exclude events that are not relevant for Thomson Reuters hosted Regions, or specific AWS services. The process of identifying events to include is a continuous iterative effort, relying on the data captured in DynamoDB tables and from experiences of different teams. AWS EventBridge simplifies the process of filtering out events by eliminating the need to develop a custom application.

ServiceNow is used to create various dashboards which are important to Thomson Reuters leadership to view the health of the AWS environment in a glance, and detailed dashboards for individual application, business units and AWS Regions are also curated for specific requirements. This solution allows Thomson Reuters to capture metrics which helps to understand the scheduled changes that AWS performs and identify the underlying resources that are impacted in different AWS accounts. The ServiceNow incidents created from Health events are used to take real-time actions to mitigate any potential issues.

Thomson Reuters has a business requirement to persist AWS Health event history for a minimum of 2 years, and a need for customized dashboards for leadership to view performance and availability metrics across applications. This necessitated the creation of dashboards in ServiceNow. Figures 2, 3, and 4 are examples of dashboards that are created to provide a comprehensive view of AWS Health events across the organization.

ServiceNow dashboard with a consolidated view of AWS Health events

Figure 2. ServiceNow dashboard with a consolidated view of AWS Health events

ServiceNow dashboard with a consolidated view of AWS Health events

Figure 3. ServiceNow dashboard with a consolidated view of AWS Health events

ServiceNow dashboard showing AWS Health events

Figure 4. ServiceNow dashboard showing AWS Health events

Datadog for account notifications

Thomson Reuters leverages Datadog as its strategic platform to observe, monitor, and track the infrastructure, applications and more. Health events with the category type Account Notification are forwarded to Datadog and are monitored by Thomson Reuters Global Command Center part of the Service Management. Account notifications are important to track as they contain information about administration or security of AWS accounts. Like ServiceNow, Datadog is also used to curate separate dashboards with unique Datadog monitors for monitoring and tracking these events (Figure 5). Currently, the Thomson Reuters Service Management team are the main consumers of these Datadog alerts, but in the future the strategy would be to route relevant and important notifications only to the concerned application team by ensuring a mandatory and robust tagging standards on the existing AWS accounts for all AWS resource types.

Datadog dashboard for AWS Health event type account notification

Figure 5. Datadog dashboard for AWS Health event type account notification

What’s next?

Thomson Reuters will continue to enhance the logic for identifying important Health events that require attention, reducing noise by filtering out unimportant ones. Thomson Reuters plan to develop a self-service subscription model, allowing application teams to opt into the Health events related to their applications.

The next key focus will also be to look at automating actions for specific AWS Health scheduled events wherever possible, such as responding to maintenance with AWS System Manager Automation documents.

Conclusion

By using this solution, Thomson Reuters can effectively monitor and track AWS Health events at scale using the preferred internal tools ServiceNow and Datadog. Integration with ServiceNow allowed Thomson Reuters to measure and track all the events and estimate the health performance with key indicators that can be generated from ServiceNow. This architecture provided an efficient way to track the AWS scheduled changes, capture metrics to understand the various schedule changes that AWS is doing and resources that are getting impacted in different AWS accounts. This solution provides actionable insights from the AWS Health events, allowing Thomson Reuters to take real-time actions to mitigate impacts to the applications and thus offer high Service levels to Thomson Reuters customers.

Automatically delete schedules upon completion with Amazon EventBridge Scheduler

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/compute/automatically-delete-schedules-upon-completion-with-amazon-eventbridge-scheduler/

Amazon EventBridge Scheduler now supports configuring automatic deletion of schedules after completion. Now you can configure one-time and recurring schedules with an end date to be automatically deleted upon completion to avoid managing individual schedules.

Amazon EventBridge Scheduler allows you to create, run, and manage schedules on scale. Using EventBridge Scheduler, you can schedule millions of tasks to invoke over 270 AWS services and over 6,000 API operations, such as AWS Lambda, AWS Step Functions, and Amazon SNS.

By default, EventBridge Scheduler allows customers to have 1 million schedules per account, which can be increased as needed. However, completed schedules are counted towards the account quota limits. In addition, completed schedules are visible when listing schedules, and require customers to remove them. Some customers have created their own patterns to automatically remove completed schedules and since the EventBridge Scheduler announcement last November, this was one of the most requested features by customers.

Deleting after completion

When you configure automatic deletion for a schedule, EventBridge Scheduler deletes the schedule shortly after its last target invocation. You can set up automatic deletion when you create the schedule, or you can update the schedule settings at any point before its last invocation.

You can configure this setting in one-time and recurring schedules.

  • One-time schedules: your schedule is deleted after the schedule has invoked its target once.
  • Recurring schedules: set with rate or cron expressions, your schedule is deleted after the last invocation.

If all retries are exhausted because of failure for a schedule configured with automatic deletion, the schedule is deleted shortly after the last unsuccessful attempt.

Console action after schedule completition

With this new capability, you can save time, resources, and operational costs when managing your schedules.

Setting up schedules to delete after completion

You can create schedules that are automatically deleted after completion from the AWS Management Console, AWS SDK, or AWS CLI in all AWS Regions where EventBridge Scheduler is available.

For example, imagine that you are a developer on a platform that allows end users to receive notifications when a task is due. You are already using EventBridge Scheduler to implement this feature. For every task that your users create in your application, your code creates a new schedule in EventBridge Scheduler. You can now configure all these schedules to be deleted automatically after completion. And shortly after the schedules run, they are removed from your EventBridge Scheduler, allowing you to scale your system and keep on creating schedules, making it easier to manage your active schedules and quota limits.

Let see how you can implement this example with the new capability of EventBridge Scheduler. When a user creates a new task with a reminder, a function is triggered from your application. That function creates a one-time schedule in EventBridge Scheduler.

Create a schedule diagram

This example shows how you can create a new one-time schedule that is automatically deleted after completion using the AWS CLI and has SNS as a target. Make sure that you update the AWS CLI to the latest version. Then you can create a new schedule with the parameter action-after-completion ‘DELETE’.

$ aws scheduler create-schedule --name SendEmailOnce \
--schedule-expression ”at(2023-08-02T17:35:00)",\
--schedule-expression-timezone "Europe/Helsinki" \
--flexible-time-window "{\"Mode\": \"OFF\"}" \
--target "{\"Arn\": \"arn:aws:sns:us-east-1:xxx:test-send-email\", \"RoleArn\": \" arn:aws:iam::xxxx:role/sam_scheduler_role\" }" \
--action-after-completion 'DELETE'

This command creates a one-time schedule with the name SendEmailOnce, that runs at a specific date, defined in the schedule-expression, and in a specific time zone, defined in the schedule-expression-timezone. This schedule is not using the flexible time window feature. Next, you must define the target for this schedule. This one sends a message to an SNS topic.

You can validate that your schedule is created correctly from the AWS CLI with the get-schedule command.

$ aws scheduler get-schedule --name SendEmailOnce
{
    "ActionAfterCompletion": "DELETE",
    "Arn": "arn:aws:scheduler:us-east-1:905614108351:schedule/default/SendEmailOnce",
    "CreationDate": 1690874334.83,
    "FlexibleTimeWindow": {
        "Mode": "OFF"
    },
    "GroupName": "default",
    "LastModificationDate": 1690874334.83,
    "Name": "SendEmailOnce3",
    "ScheduleExpression": "at(2023-08-02T17:35:00)",
    "ScheduleExpressionTimezone": "Europe/Helsinki",
    "State": "ENABLED",
    "Target": {
        "Arn": "arn:aws:sns:us-east-1:xxxx:test-send-email",
        "RetryPolicy": {
            "MaximumEventAgeInSeconds": 86400,
            "MaximumRetryAttempts": 185
        },
        "RoleArn": "arn:aws:iam::XXXX:role/scheduler_role"
    }
}

In addition, you can see the details of the schedule from the AWS Management Console.

Schedule details

Now when the date of the notification arrives, EventBridge Scheduler invokes the target configured in the schedule, in this case SNS, and emails a notification to the customer.

Schedule starts

Shortly after this schedule is completed, if you list the schedules, you see that the schedule was deleted and it is no longer listed.

$ aws scheduler list-schedules
{
"Schedules": [
]
}

Benefits of automation

Traditionally, many problems that EventBridge Scheduler solves were addressed using batch processes and pull-based models.

Some organizations are using EventBridge Scheduler to replace their pull-based models for a more dynamic push-based model. Before implementing Scheduler, they were relying on the customer to ask for the data when they need it. Now, with EventBridge Scheduler, they are creating schedules to report back to their customers at critical times of their journey.

For example, an airline can use EventBridge Scheduler to create one-time schedules 24 hours, 4 hours, and 2 hours before the flight, to keep their passengers up to date with the flight status. Customers receive a notification with the link for the online check-in, the check-in counter number, baggage pick up information, and any flight changes that occur. In this way, passengers are always up to date on their flight status and they can take immediate action. This dynamic model not only helps to improve the customer experience but also improves the operational efficiency for the airline.

Other organizations use EventBridge Scheduler to replace batch operations, as you can configure a schedule that starts a batch process at the time of the day you need. Also, you can take advantage of EventBridge Scheduler time zones and run the processes at the time that make sense for your end customer.

For example, consider an international financial institution that must send customers a statement of their account at the end of the day. You can use EventBridge Scheduler to set up a recurrent schedule for each of your customers that sends a report at the end of the day of your customers’ time zone. In this way, you can improve the customer experience as now the system is personalized for their settings, and also reduce operational overhead, as the processing operations are distributed throughout the day.

In addition, EventBridge Scheduler solves many new use cases for customers. For example, if you are a financial institution that handles payments, you can create a one-time schedule for every large transaction that needs a confirmation. If the transaction is not confirmed when the schedule runs, you can cancel the transaction. This decreases the risk of handling transactions, improves the customer experience, and also improves the automation of your processes by making them real time.

Another use case is to handle credit card expiration dates. You can create a one-time schedule that emails the customer to update their credit card information one month before the expiration date. This solution removes operational overhead compared to the traditional implementation of using servers and batch processes.

Conclusion

In the preceding use cases listed, automation and task scheduling improve the end user experience, remove undifferentiated heavy lifting, and benefit from using the new capability of removing schedules after their completion.

This blog post introduces the new capability from Amazon EventBridge Scheduler that automatically deletes the completed schedules. This feature simplifies the use of EventBridge Scheduler, reduces the operational overhead of managing schedules at scale, and allows you to scale even further.

To get started with EventBridge Scheduler, visit Serverless Land patterns where you can find over 20 patterns using this service.

Perform continuous vulnerability scanning of AWS Lambda functions with Amazon Inspector

Post Syndicated from Manjunath Arakere original https://aws.amazon.com/blogs/security/perform-continuous-vulnerability-scanning-of-aws-lambda-functions-with-amazon-inspector/

This blog post demonstrates how you can activate Amazon Inspector within one or more AWS accounts and be notified when a vulnerability is detected in an AWS Lambda function.

Amazon Inspector is an automated vulnerability management service that continually scans workloads for software vulnerabilities and unintended network exposure. Amazon Inspector scans mixed workloads like Amazon Elastic Compute Cloud (Amazon EC2) instances and container images located in Amazon Elastic Container Registry (Amazon ECR). At re:Invent 2022, we announced Amazon Inspector support for Lambda functions and Lambda layers to provide a consolidated solution for compute types.

Only scanning your functions for vulnerabilities before deployment might not be enough since vulnerabilities can appear at any time, like the widespread Apache Log4j vulnerability. So it’s essential that workloads are continuously monitored and rescanned in near real time as new vulnerabilities are published or workloads are changed.

Amazon Inspector scans are intelligently initiated based on the updates to Lambda functions or when new Common Vulnerabilities and Exposures (CVEs) are published that are relevant to your function. No agents are needed for Amazon Inspector to work, which means you don’t need to install a library or agent in your Lambda functions or layers. When Amazon Inspector discovers a software vulnerability or network configuration issue, it creates a finding which describes the vulnerability, identifies the affected resource, rates the severity of the vulnerability, and provides remediation guidance.

In addition, Amazon Inspector integrates with several AWS services, such as Amazon EventBridge and AWS Security Hub. You can use EventBridge to build automation workflows like getting notified for a specific vulnerability finding or performing an automatic remediation with the help of Lambda or AWS Systems Manager.

In this blog post, you will learn how to do the following:

  1. Activate Amazon Inspector in a single AWS account and AWS Region.
  2. See how Amazon Inspector automated discovery and continuous vulnerability scanning works by deploying a new Lambda function with a vulnerable package dependency.
  3. Receive a near real-time notification when a vulnerability with a specific severity is detected in a Lambda function with the help of EventBridge and Amazon Simple Notification Service (Amazon SNS).
  4. Remediate the vulnerability by using the recommendation provided in the Amazon Inspector dashboard.
  5. Activate Amazon Inspector in multiple accounts or Regions through AWS Organizations.

Solution architecture

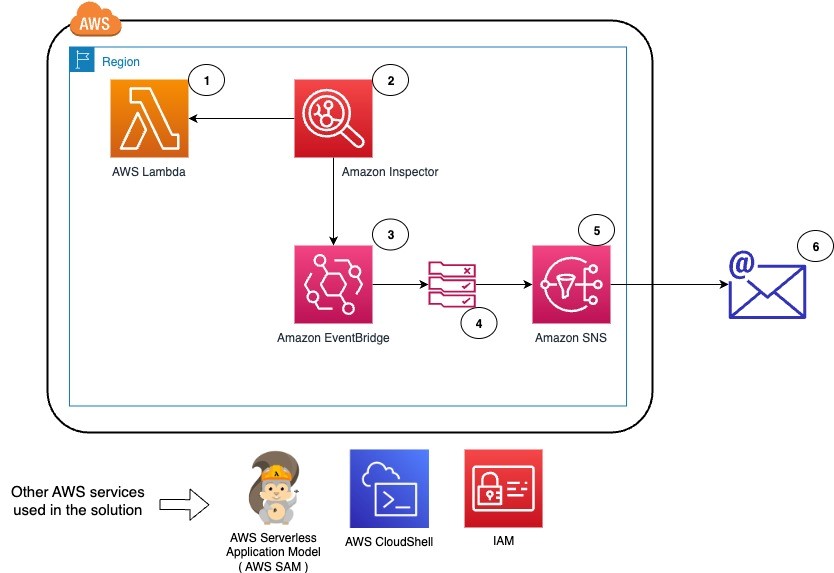
Figure 1 shows the AWS services used in the solution and how they are integrated.

Figure 1: Solution architecture overview

Figure 1: Solution architecture overview

The workflow for the solution is as follows:

  1. Deploy a new Lambda function by using the AWS Serverless Application Model (AWS SAM).
  2. Amazon Inspector scans when a new vulnerability is published or when an update to an existing Lambda function or a new Lambda function is deployed. Vulnerabilities are identified in the deployed Lambda function.
  3. Amazon EventBridge receives the events from Amazon Inspector and checks against the rules for specific events or filter conditions.
  4. In this case, an EventBridge rule exists for the Amazon Inspector findings, and the target is defined as an SNS topic to send an email to the system operations team.
  5. The EventBridge rule invokes the target SNS topic with the event data, and an email is sent to the confirmed subscribers in the SNS topic.
  6. The system operations team receives an email with detailed information on the vulnerability, the fixed package versions, the Amazon Inspector score to prioritize, and the impacted Lambda functions. By using the remediation information from Amazon Inspector, the team can now prioritize actions and remediate.

Prerequisites

To follow along with this demo, we recommend that you have the following in place:

  • An AWS account.
  • A command line interface: AWS CloudShell or AWS CLI. In this post, we recommend the use of CloudShell because it already has Python and AWS SAM. However, you can also use your CLI with AWS CLI, SAM, and Python.
  • An AWS Region where Amazon Inspector Lambda code scanning is available.
  • An IAM role in that account with administrator privileges.

The solution in this post includes the following AWS services: Amazon Inspector, AWS Lambda, Amazon EventBridge, AWS Identity and Access Management (IAM), Amazon SNS, AWS CloudShell and AWS Organizations for activating Amazon Inspector at scale (multi-accounts).

Step 1: Activate Amazon Inspector in a single account in the Region

The first step is to activate Amazon Inspector in your account in the Region you are using.

To activate Amazon Inspector

  1. Sign in to the AWS Management Console.
  2. Open AWS CloudShell. CloudShell inherits the credentials and permissions of the IAM principal who is signed in to the AWS Management Console. CloudShell comes with the CLIs and runtimes that are needed for this demo (AWS CLI, AWS SAM, and Python).
  3. Use the following command in CloudShell to get the status of the Amazon Inspector activation.
    aws inspector2 batch-get-account-status

  4. Use the following command to activate Inspector in the default Region for resource type LAMBDA. Other allowed values for resource types are EC2, ECR and LAMDA_CODE.
    aws inspector2 enable --resource-types '["LAMBDA"]'

  5. Use the following command to verify the status of the Amazon Inspector activation.
    aws inspector2 batch-get-account-status

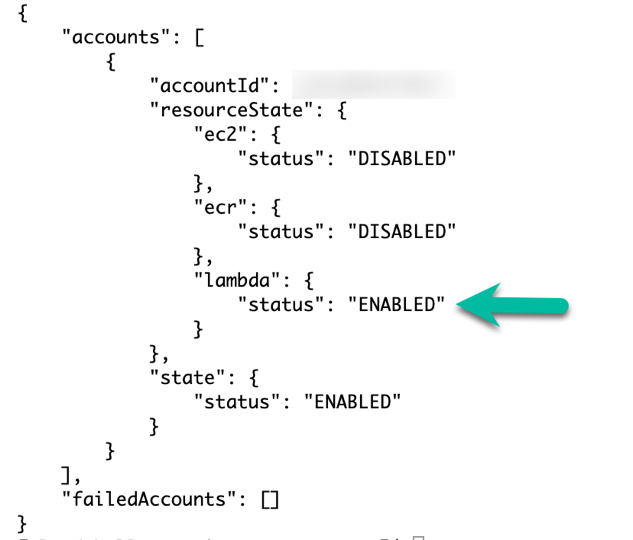
You should see a response that shows that Amazon Inspector is enabled for Lambda resources, as shown in Figure 2.

Figure 2: Amazon Inspector status after you enable Lambda scanning

Figure 2: Amazon Inspector status after you enable Lambda scanning

Step 2: Create an SNS topic and subscription for notification

Next, create the SNS topic and the subscription so that you will be notified of each new Amazon Inspector finding.

To create the SNS topic and subscription

  1. Use the following command in CloudShell to create the SNS topic and its subscription and replace <REGION_NAME>, <AWS_ACCOUNTID> and <[email protected]> by the relevant values.
    aws sns create-topic --name amazon-inspector-findings-notifier; 
    
    aws sns subscribe \
    --topic-arn arn:aws:sns:<REGION_NAME>:<AWS_ACCOUNTID>:amazon-inspector-findings-notifier \
    --protocol email --notification-endpoint <[email protected]>

  2. Check the email inbox you entered for <[email protected]>, and in the email from Amazon SNS, choose Confirm subscription.
  3. In the CloudShell console, use the following command to list the subscriptions, to verify the topic and email subscription.
    aws sns list-subscriptions

    You should see a response that shows subscription details like the email address and ARN, as shown in Figure 3.

    Figure 3: Subscribed email address and SNS topic

    Figure 3: Subscribed email address and SNS topic

  4. Use the following command to send a test message to your subscribed email and verify that you receive the message by replacing <REGION_NAME> and <AWS_ACCOUNTID>.
    aws sns publish \
        --topic-arn "arn:aws:sns:<REGION_NAME>:<AWS_ACCOUNTID>:amazon-inspector-findings-notifier" \
        --message "Hello from Amazon Inspector2"

Step 3: Set up Amazon EventBridge with a custom rule and the SNS topic as target

Create an EventBridge rule that will invoke your previously created SNS topic whenever Amazon Inspector finds a new vulnerability with a critical severity.

To set up the EventBridge custom rule

  1. In the CloudShell console, use the following command to create an EventBridge rule named amazon-inspector-findings with filters InspectorScore greater than 8 and severity state set to CRITICAL.
    aws events put-rule \
        --name "amazon-inspector-findings" \
        --event-pattern "{\"source\": [\"aws.inspector2\"],\"detail-type\": [\"Inspector2 Finding\"],\"detail\": {\"inspectorScore\": [ { \"numeric\": [ \">\", 8] } ],\"severity\": [\"CRITICAL\"]}}"

    Refer to the topic Amazon EventBridge event schema for Amazon Inspector events to customize the event pattern for your application needs.

  2. To verify the rule creation, go to the EventBridge console and in the left navigation bar, choose Rules.
  3. Choose the rule with the name amazon-inspector-findings. You should see the event pattern as shown in Figure 4.
    Figure 4: Event pattern for the EventBridge rule to filter on CRITICAL vulnerabilities.

    Figure 4: Event pattern for the EventBridge rule to filter on CRITICAL vulnerabilities.

  4. Add the SNS topic you previously created as the target to the EventBridge rule. Replace <REGION_NAME>, <AWS_ACCOUNTID>, and <RANDOM-UNIQUE-IDENTIFIER-VALUE> with the relevant values. For RANDOM-UNIQUE-IDENTIFIER-VALUE, create a memorable and unique string.
    aws events put-targets \
        --rule amazon-inspector-findings \
        --targets "Id"="<RANDOM-UNIQUE-IDENTIFIER-VALUE>","Arn"="arn:aws:sns:<REGION_NAME>:<AWS_ACCOUNTID>:amazon-inspector-findings-notifier"

    Important: Save the target ID. You will need this in order to delete the target in the last step.

  5. Provide permission to enable Amazon EventBridge to publish to SNS topic amazon-inspector-findings-notifier
    aws sns set-topic-attributes --topic-arn "arn:aws:sns:<REGION_NAME>:<AWS_ACCOUNTID>:amazon-inspector-findings-notifier" \
    --attribute-name Policy \
    --attribute-value "{\"Version\":\"2012-10-17\",\"Id\":\"__default_policy_ID\",\"Statement\":[{\"Sid\":\"PublishEventsToMyTopic\",\"Effect\":\"Allow\",\"Principal\":{\"Service\":\"events.amazonaws.com\"},\"Action\":\"sns:Publish\",\"Resource\":\"arn:aws:sns:<REGION_NAME>:<AWS_ACCOUNTID>:amazon-inspector-findings-notifier\"}]}"

Step 4: Deploy the Lambda function to the AWS account by using AWS SAM

In this step, you will use Serverless Application Manager (SAM) quick state templates to build and deploy a Lambda function with a vulnerable library, in order to generate findings. Learn more about AWS SAM.

To deploy the Lambda function with a vulnerable library

  1. In the CloudShell console, use a prebuilt “hello-world” AWS SAM template to deploy the Lambda function.
    sam init --runtime python3.7 --dependency-manager pip --app-template hello-world --name sam-app

  2. Use the following command to add the vulnerable package python-jwt==3.3.3 to the Lambda function.
    cd sam-app;
    echo -e 'requests\npython-jwt==3.3.3' > hello_world/requirements.txt

  3. Use the following command to build the application.
    sam build

  4. Use the following command to deploy the application with the guided option.
    sam deploy --guided

    This command packages and deploys the application to your AWS account. It provides a series of prompts. You may respond to the prompts with the:

    1. Stack name you want
    2. Set the default options, except for the
      1. HelloWorldFunction may not have authorization defined, Is this okay? [y/N]: prompt. Here, input y and press Enter and
      2. Deploy this changeset? [y/N]: prompt. Here, input y and press Enter.

Step 5: View Amazon Inspector findings

Amazon Inspector will automatically generate findings when scanning the Lambda function previously deployed. To view those findings, follow the steps below.

To view Amazon Inspector findings for the vulnerability

  1. Navigate to the Amazon Inspector console.
  2. In the left navigation menu, choose All findings to see all of the Active findings, as shown in Figure 5.

    Due to the custom event pattern rule in Amazon EventBridge, even though there are multiple findings for the vulnerable package python-jwt==3.3.3, you will be notified only for the finding that has InspectorScore greater than 8 and severity CRITICAL.

  3. Choose the title of each finding to see detailed information about the vulnerability.
    Figure 5: Example of findings from the Amazon Inspector console

    Figure 5: Example of findings from the Amazon Inspector console

Step 6: Remediate the vulnerability by applying the fixed package version

Now you can remediate the vulnerability by updating the package version as suggested by Amazon Inspector.

To remediate the vulnerability

  1. In the Amazon Inspector console, in the left navigation menu, choose All Findings.
  2. Choose the title of the vulnerability to see the finding details and the remediation recommendations.
    Figure 6: Amazon Inspector finding for python-jwt, with the associated remediation

    Figure 6: Amazon Inspector finding for python-jwt, with the associated remediation

  3. To remediate, use the following command to update the package version to the fixed version as suggested by Amazon Inspector.
    cd /home/cloudshell-user/sam-app;
    echo -e "requests\npython-jwt==3.3.4" > hello_world/requirements.txt

  4. Use the following command to build the application.
    sam build

  5. Use the following command to deploy the application with the guided option.
    sam deploy --guided

    This command packages and deploys the application to your AWS account. It provides a series of prompts. You may respond to the prompts with the

    1. Stack name you want
    2. Set the default options, except for the
      1. HelloWorldFunction may not have authorization defined, Is this okay? [y/N]: prompt. Here, input y and press Enter and
      2. Deploy this changeset? [y/N]: prompt. Here, input y and press Enter.
  6. Amazon Inspector automatically rescans the function after its deployment and reevaluates the findings. At this point, you can navigate back to the Amazon Inspector console, and in the left navigation menu, choose All findings. In the Findings area, you can see that the vulnerabilities are moved from Active to Closed status.

    Due to the custom event pattern rule in Amazon EventBridge, you will be notified by email with finding status as CLOSED.

    Figure 7: Inspector rescan results, showing no open findings after remediation

    Figure 7: Inspector rescan results, showing no open findings after remediation

(Optional) Step 7: Activate Amazon Inspector in multiple accounts and Regions

To benefit from Amazon Inspector scanning capabilities across the accounts that you have in AWS Organizations and in your selected Regions, use the following steps:

To activate Amazon Inspector in multiple accounts and Regions

  1. In the CloudShell console, use the following command to clone the code from the aws-samples inspector2-enablement-with-cli GitHub repo.
    cd /home/cloudshell-user;
    git clone https://github.com/aws-samples/inspector2-enablement-with-cli.git;
    cd inspector2-enablement-with-cli

  2. Follow the instructions from the README.md file.
  3. Configure the file param_inspector2.json with the relevant values, as follows:
    • inspector2_da: The delegated administrator account ID for Amazon Inspector to manage member accounts.
    • scanning_type: The resource types (EC2, ECR, LAMBDA) to be enabled by Amazon Inspector.
    • auto_enable: The resource types to be enabled on every account that is newly attached to the delegated administrator.
    • regions: Because Amazon Inspector is a regional service, provide the list of AWS Regions to enable.
  4. Select the AWS account that would be used as the delegated administrator account (<DA_ACCOUNT_ID>).
  5. Delegate an account as the admin for Amazon Inspector by using the following command.
    ./inspector2_enablement_with_awscli.sh -a delegate_admin -da <DA_ACCOUNT_ID>

  6. Activate the delegated admin by using the following command:
    ./inspector2_enablement_with_awscli.sh -a activate -t <DA_ACCOUNT_ID> -s all

  7. Associate the member accounts by using the following command:
    ./inspector2_enablement_with_awscli.sh -a associate -t members

  8. Wait five minutes.
  9. Enable the resource types (EC2, ECR, LAMBDA) on your member accounts by using the following command:
    ./inspector2_enablement_with_awscli.sh -a activate -t members

  10. Enable Amazon Inspector on the new member accounts that are associated with the organization by using the following command:
    ./inspector2_enablement_with_awscli.sh -auto_enable

  11. Check the Amazon Inspector status in your accounts and in multiple selected Regions by using the following command:
    ./inspector2_enablement_with_awscli.sh -a get_status

There are other options you can use to enable Amazon Inspector in multiple accounts, like AWS Control Tower and Terraform. For the reference architecture for Control Tower, see the AWS Security Reference Architecture Examples on GitHub. For more information on the Terraform option, see the Terraform aws_inspector2_enabler resource page.

Step 8: Delete the resources created in the previous steps

AWS offers a 15-day free trial for Amazon Inspector so that you can evaluate the service and estimate its cost.

To avoid potential charges, delete the AWS resources that you created in the previous steps of this solution (Lambda function, EventBridge target, EventBridge rule, and SNS topic), and deactivate Amazon Inspector.

To delete resources

  1. In the CloudShell console, enter the sam-app folder.
    cd /home/cloudshell-user/sam-app

  2. Delete the Lambda function and confirm by typing “y” when prompted for confirmation.
    sam delete

  3. Remove the SNS target from the Amazon EventBridge rule.
    aws events remove-targets --rule "amazon-inspector-findings" --ids <RANDOM-UNIQUE-IDENTIFIER-VALUE>

    Note: If you don’t remember the target ID, navigate to the Amazon EventBridge console, and in the left navigation menu, choose Rules. Select the rule that you want to delete. Choose CloudFormation, and copy the ID.

  4. Delete the EventBridge rule.
    aws events delete-rule --name amazon-inspector-findings

  5. Delete the SNS topic.
    aws sns delete-topic --topic-arn arn:aws:sns:<REGION_NAME>:<AWS_ACCOUNTID>:amazon-inspector-findings-notifier

  6. Disable Amazon Inspector.
    aws inspector2 disable --resource-types '["LAMBDA"]'

    Follow the new few steps to roll back changes only if you have performed the activities listed in Step 7: Activate Amazon Inspector in multiple accounts and Regions.

  7. In the CloudShell console, enter the folder inspector2-enablement-with-cli.
    cd /home/cloudshell-user/inspector2-enablement-with-cli

  8. Deactivate the resource types (EC2, ECR, LAMBDA) on your member accounts.
    ./inspector2_enablement_with_awscli.sh -a deactivate -t members -s all

  9. Disassociate the member accounts.
    ./inspector2_enablement_with_awscli.sh -a disassociate -t members

  10. Deactivate the delegated admin account.
    ./inspector2_enablement_with_awscli.sh -a deactivate -t <DA_ACCOUNT_ID> -s all

  11. Remove the delegated account as the admin for Amazon Inspector.
    ./inspector2_enablement_with_awscli.sh -a remove_admin -da <DA_ACCOUNT_ID>

Conclusion

In this blog post, we discussed how you can use Amazon Inspector to continuously scan your Lambda functions, and how to configure an Amazon EventBridge rule and SNS to send out notification of Lambda function vulnerabilities in near real time. You can then perform remediation activities by using AWS Lambda or AWS Systems Manager. We also showed how to enable Amazon Inspector at scale, activating in both single and multiple accounts, in default and multiple Regions.

As of the writing this post, a new feature to perform code scans for Lambda functions is available. Amazon Inspector can now also scan the custom application code within a Lambda function for code security vulnerabilities such as injection flaws, data leaks, weak cryptography, or missing encryption, based on AWS security best practices. You can use this additional scanning functionality to further protect your workloads.

If you have feedback about this blog post, submit comments in the Comments section below. If you have question about this blog post, start a new thread on the Amazon Inspector forum or contact AWS Support.

 
Want more AWS Security news? Follow us on Twitter.

Manjunath Arakere

Manjunath Arakere

Manjunath is a Senior Solutions Architect in the Worldwide Public Sector team at AWS. He works with Public Sector partners to design and scale well-architected solutions, and he supports their cloud migrations and application modernization initiatives. Manjunath specializes in migration, modernization and serverless technology.

Stéphanie Mbappe

Stéphanie Mbappe

Stéphanie is a Security Consultant with Amazon Web Services. She delights in assisting her customers at every step of their security journey. Stéphanie enjoys learning, designing new solutions, and sharing her knowledge with others.

How to Receive Alerts When Your IAM Configuration Changes

Post Syndicated from Dylan Souvage original https://aws.amazon.com/blogs/security/how-to-receive-alerts-when-your-iam-configuration-changes/

July 27, 2023: This post was originally published February 5, 2015, and received a major update July 31, 2023.


As an Amazon Web Services (AWS) administrator, it’s crucial for you to implement robust protective controls to maintain your security configuration. Employing a detective control mechanism to monitor changes to the configuration serves as an additional safeguard in case the primary protective controls fail. Although some changes are expected, you might want to review unexpected changes or changes made by a privileged user. AWS Identity and Access Management (IAM) is a service that primarily helps manage access to AWS services and resources securely. It does provide detailed logs of its activity, but it doesn’t inherently provide real-time alerts or notifications. Fortunately, you can use a combination of AWS CloudTrail, Amazon EventBridge, and Amazon Simple Notification Service (Amazon SNS) to alert you when changes are made to your IAM configuration. In this blog post, we walk you through how to set up EventBridge to initiate SNS notifications for IAM configuration changes. You can also have SNS push messages directly to ticketing or tracking services, such as Jira, Service Now, or your preferred method of receiving notifications, but that is not discussed here.

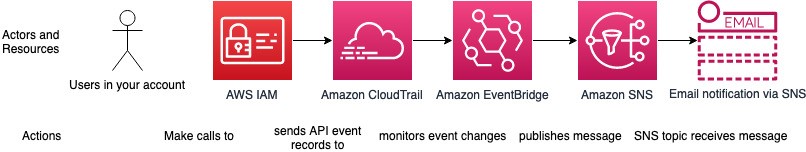
In any AWS environment, many activities can take place at every moment. CloudTrail records IAM activities, EventBridge filters and routes event data, and Amazon SNS provides notification functionality. This post will guide you through identifying and setting alerts for IAM changes, modifications in authentication and authorization configurations, and more. The power is in your hands to make sure you’re notified of the events you deem most critical to your environment. Here’s a quick overview of how you can invoke a response, shown in Figure 1.

Figure 1: Simple architecture diagram of actors and resources in your account and the process for sending notifications through IAM, CloudTrail, EventBridge, and SNS.

Figure 1: Simple architecture diagram of actors and resources in your account and the process for sending notifications through IAM, CloudTrail, EventBridge, and SNS.

Log IAM changes with CloudTrail

Before we dive into implementation, let’s briefly understand the function of AWS CloudTrail. It records and logs activity within your AWS environment, tracking actions such as IAM role creation, deletion, or modification, thereby offering an audit trail of changes.

With this in mind, we’ll discuss the first step in tracking IAM changes: establishing a log for each modification. In this section, we’ll guide you through using CloudTrail to create these pivotal logs.

For an in-depth understanding of CloudTrail, refer to the AWS CloudTrail User Guide.

In this post, you’re going to start by creating a CloudTrail trail with the Management events type selected, and read and write API activity selected. If you already have a CloudTrail trail set up with those attributes, you can use that CloudTrail trail instead.

To create a CloudTrail log

  1. Open the AWS Management Console and select CloudTrail, and then choose Dashboard.
  2. In the CloudTrail dashboard, choose Create Trail.
    Figure 2: Use the CloudTrail dashboard to create a trail

    Figure 2: Use the CloudTrail dashboard to create a trail

  3. In the Trail name field, enter a display name for your trail and then select Create a new S3 bucket. Leave the default settings for the remaining trail attributes.
    Figure 3: Set the trail name and storage location

    Figure 3: Set the trail name and storage location

  4. Under Event type, select Management events. Under API activity, select Read and Write.
  5. Choose Next.
    Figure 4: Choose which events to log

    Figure 4: Choose which events to log

Set up notifications with Amazon SNS

Amazon SNS is a managed service that provides message delivery from publishers to subscribers. It works by allowing publishers to communicate asynchronously with subscribers by sending messages to a topic, a logical access point, and a communication channel. Subscribers can receive these messages using supported endpoint types, including email, which you will use in the blog example today.

For further reading on Amazon SNS, refer to the Amazon SNS Developer Guide.

Now that you’ve set up CloudTrail to log IAM changes, the next step is to establish a mechanism to notify you about these changes in real time.

To set up notifications

  1. Open the Amazon SNS console and choose Topics.
  2. Create a new topic. Under Type, select Standard and enter a name for your topic. Keep the defaults for the rest of the options, and then choose Create topic.
    Figure 5: Select Standard as the topic type

    Figure 5: Select Standard as the topic type

  3. Navigate to your topic in the topic dashboard, choose the Subscriptions tab, and then choose Create subscription.
    Figure 6: Choose Create subscription

    Figure 6: Choose Create subscription

  4. For Topic ARN, select the topic you created previously, then under Protocol, select Email and enter the email address you want the alerts to be sent to.
    Figure 7: Select the topic ARN and add an endpoint to send notifications to

    Figure 7: Select the topic ARN and add an endpoint to send notifications to

  5. After your subscription is created, go to the mailbox you designated to receive notifications and check for a verification email from the service. Open the email and select Confirm subscription to verify the email address and complete setup.

Initiate events with EventBridge

Amazon EventBridge is a serverless service that uses events to connect application components. EventBridge receives an event (an indicator of a change in environment) and applies a rule to route the event to a target. Rules match events to targets based on either the structure of the event, called an event pattern, or on a schedule.

Events that come to EventBridge are associated with an event bus. Rules are tied to a single event bus, so they can only be applied to events on that event bus. Your account has a default event bus that receives events from AWS services, and you can create custom event buses to send or receive events from a different account or AWS Region.

For a more comprehensive understanding of EventBridge, refer to the Amazon EventBridge User Guide.

In this part of our post, you’ll use EventBridge to devise a rule for initiating SNS notifications based on IAM configuration changes.

To create an EventBridge rule

  1. Go to the EventBridge console and select EventBridge Rule, and then choose Create rule.
    Figure 8: Use the EventBridge console to create a rule

    Figure 8: Use the EventBridge console to create a rule

  2. Enter a name for your rule, keep the defaults for the rest of rule details, and then choose Next.
    Figure 9: Rule detail screen

    Figure 9: Rule detail screen

  3. Under Target 1, select AWS service.
  4. In the dropdown list for Select a target, select SNS topic, select the topic you created previously, and then choose Next.
    Figure 10: Target with target type of AWS service and target topic of SNS topic selected

    Figure 10: Target with target type of AWS service and target topic of SNS topic selected

  5. Under Event source, select AWS events or EventBridge partner events.
    Figure 11: Event pattern with AWS events or EventBridge partner events selected

    Figure 11: Event pattern with AWS events or EventBridge partner events selected

  6. Under Event pattern, verify that you have the following selected.
    1. For Event source, select AWS services.
    2. For AWS service, select IAM.
    3. For Event type, select AWS API Call via CloudTrail.
    4. Select the radio button for Any operation.
    Figure 12: Event pattern details selected

    Figure 12: Event pattern details selected

Now that you’ve set up EventBridge to monitor IAM changes, test it by creating a new user or adding a new policy to an IAM role and see if you receive an email notification.

Centralize EventBridge alerts by using cross-account alerts

If you have multiple accounts, you should be evaluating using AWS Organizations. (For a deep dive into best practices for using AWS Organizations, we recommend reading this AWS blog post.)

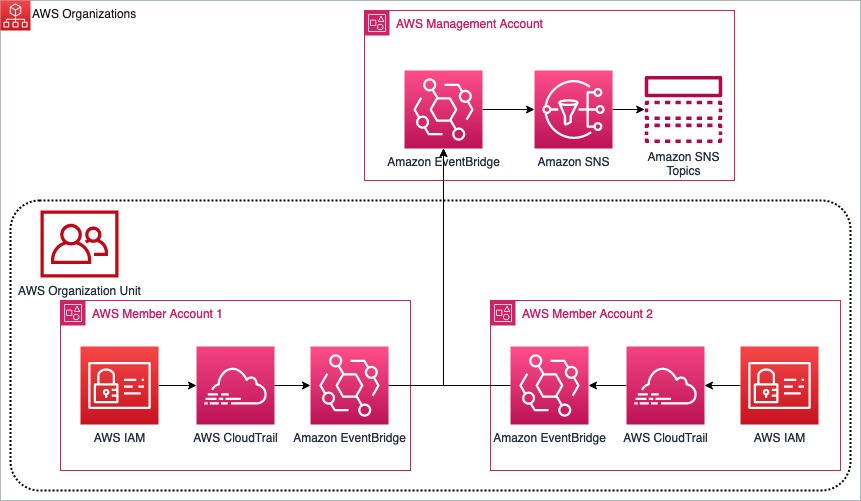
By standardizing the implementation to channel alerts from across accounts to a primary AWS notification account, you can use a multi-account EventBridge architecture. This allows aggregation of notifications across your accounts through sender and receiver accounts. Figure 13 shows how this works. Separate member accounts within an AWS organizational unit (OU) have the same mechanism for monitoring changes and sending notifications as discussed earlier, but send notifications through an EventBridge instance in another account.

Figure 13: Multi-account EventBridge architecture aggregating notifications between two AWS member accounts to a primary management account

Figure 13: Multi-account EventBridge architecture aggregating notifications between two AWS member accounts to a primary management account

You can read more and see the implementation and deep dive of the multi-account EventBridge solution on the AWS samples GitHub, and you can also read more about sending and receiving Amazon EventBridge notifications between accounts.

Monitor calls to IAM

In this blog post example, you monitor calls to IAM.

The filter pattern you selected while setting up EventBridge matches CloudTrail events for calls to the IAM service. Calls to IAM have a CloudTrail eventSource of iam.amazonaws.com, so IAM API calls will match this pattern. You will find this simple default filter pattern useful if you have minimal IAM activity in your account or to test this example. However, as your account activity grows, you’ll likely receive more notifications than you need. This is when filtering only the relevant events becomes essential to prioritize your responses. Effectively managing your filter preferences allows you to focus on events of significance and maintain control as your AWS environment grows.

Monitor changes to IAM

If you’re interested only in changes to your IAM account, you can modify the event pattern inside EventBridge, the one you used to set up IAM notifications, with an eventName filter pattern, shown following.

"eventName": [
      "Add*",
      "Attach*",
      "Change*",
      "Create*",
      "Deactivate*",
      "Delete*",
      "Detach*",
      "Enable*",
      "Put*",
      "Remove*",
      "Set*",
      "Update*",
      "Upload*"
    ]

This filter pattern will only match events from the IAM service that begin with Add, Change, Create, Deactivate, Delete, Enable, Put, Remove, Update, or Upload. For more information about APIs matching these patterns, see the IAM API Reference.

To edit the filter pattern to monitor only changes to IAM

  1. Open the EventBridge console, navigate to the Event pattern, and choose Edit pattern.
    Figure 14: Modifying the event pattern

    Figure 14: Modifying the event pattern

  2. Add the eventName filter pattern from above to your event pattern.
    Figure 15: Use the JSON editor to add the eventName filter pattern

    Figure 15: Use the JSON editor to add the eventName filter pattern

Monitor changes to authentication and authorization configuration

Monitoring changes to authentication (security credentials) and authorization (policy) configurations is critical, because it can alert you to potential security vulnerabilities or breaches. For instance, unauthorized changes to security credentials or policies could indicate malicious activity, such as an attempt to gain unauthorized access to your AWS resources. If you’re only interested in these types of changes, use the preceding steps to implement the following filter pattern.

    "eventName": [
      "Put*Policy",
      "Attach*",
      "Detach*",
      "Create*",
      "Update*",
      "Upload*",
      "Delete*",
      "Remove*",
      "Set*"
    ]

This filter pattern matches calls to IAM that modify policy or create, update, upload, and delete IAM elements.

Conclusion

Monitoring IAM security configuration changes allows you another layer of defense against the unexpected. Balancing productivity and security, you might grant a user broad permissions in order to facilitate their work, such as exploring new AWS services. Although preventive measures are crucial, they can potentially restrict necessary actions. For example, a developer may need to modify an IAM role for their task, an alteration that could pose a security risk. This change, while essential for their work, may be undesirable from a security standpoint. Thus, it’s critical to have monitoring systems alongside preventive measures, allowing necessary actions while maintaining security.

Create an event rule for IAM events that are important to you and have a response plan ready. You can refer to Security best practices in IAM for further reading on this topic.

If you have questions or feedback about this or any other IAM topic, please visit the IAM re:Post forum. You can also read about the multi-account EventBridge solution on the AWS samples GitHub and learn more about sending and receiving Amazon EventBridge notifications between accounts.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Dylan Souvage

Dylan Souvage

Dylan is a Solutions Architect based in Toronto, Canada. Dylan loves working with customers to understand their business and enable them in their cloud journey. In his spare time, he enjoys martial arts, sports, anime, and traveling to warm, sunny places to spend time with his friends and family.

Abhra Sinha

Abhra Sinha

Abhra is a Toronto-based Enterprise Solutions Architect at AWS. Abhra enjoys being a trusted advisor to customers, working closely with them to solve their technical challenges and help build a secure, scalable architecture on AWS. In his spare time, he enjoys Photography and exploring new restaurants.

Best practices for implementing event-driven architectures in your organization

Post Syndicated from Emanuele Levi original https://aws.amazon.com/blogs/architecture/best-practices-for-implementing-event-driven-architectures-in-your-organization/

Event-driven architectures (EDA) are made up of components that detect business actions and changes in state, and encode this information in event notifications. Event-driven patterns are becoming more widespread in modern architectures because:

  • they are the main invocation mechanism in serverless patterns.
  • they are the preferred pattern for decoupling microservices, where asynchronous communications and event persistence are paramount.
  • they are widely adopted as a loose-coupling mechanism between systems in different business domains, such as third-party or on-premises systems.

Event-driven patterns have the advantage of enabling team independence through the decoupling and decentralization of responsibilities. This decentralization trend in turn, permits companies to move with unprecedented agility, enhancing feature development velocity.

In this blog, we’ll explore the crucial components and architectural decisions you should consider when adopting event-driven patterns, and provide some guidance on organizational structures.

Division of responsibilities

The communications flow in EDA (see What is EDA?) is initiated by the occurrence of an event. Most production-grade event-driven implementations have three main components, as shown in Figure 1: producers, message brokers, and consumers.

Three main components of an event-driven architecture

Figure 1. Three main components of an event-driven architecture

Producers, message brokers, and consumers typically assume the following roles:

Producers

Producers are responsible for publishing the events as they happen. They are the owners of the event schema (data structure) and semantics (meaning of the fields, such as the meaning of the value of an enum field). As this is the only contract (coupling) between producers and the downstream components of the system, the schema and its semantics are crucial in EDA. Producers are responsible for implementing a change management process, which involves both non-breaking and breaking changes. With introduction of breaking changes, consumers are able to negotiate the migration process with producers.

Producers are “consumer agnostic”, as their boundary of responsibility ends when an event is published.

Message brokers

Message brokers are responsible for the durability of the events, and will keep an event available for consumption until it is successfully processed. Message brokers ensure that producers are able to publish events for consumers to consume, and they regulate access and permissions to publish and consume messages.

Message brokers are largely “events agnostic”, and do not generally access or interpret the event content. However, some systems provide a routing mechanism based on the event payload or metadata.

Consumers

Consumers are responsible for consuming events, and own the semantics of the effect of events. Consumers are usually bounded to one business context. This means the same event will have different effect semantics for different consumers. Crucial architectural choices when implementing a consumer involve the handling of unsuccessful message deliveries or duplicate messages. Depending on the business interpretation of the event, when recovering from failure a consumer might permit duplicate events, such as with an idempotent consumer pattern.

Crucially, consumers are “producer agnostic”, and their boundary of responsibility begins when an event is ready for consumption. This allows new consumers to onboard into the system without changing the producer contracts.

Team independence

In order to enforce the division of responsibilities, companies should organize their technical teams by ownership of producers, message brokers, and consumers. Although the ownership of producers and consumers is straightforward in an EDA implementation, the ownership of the message broker may not be. Different approaches can be taken to identify message broker ownership depending on your organizational structure.

Decentralized ownership

Ownership of the message broker in a decentralized ownership organizational structure

Figure 2. Ownership of the message broker in a decentralized ownership organizational structure

In a decentralized ownership organizational structure (see Figure 2), the teams producing events are responsible for managing their own message brokers and the durability and availability of the events for consumers.

The adoption of topic fanout patterns based on Amazon Simple Queue Service (SQS) and Amazon Simple Notification Service (SNS) (see Figure 3), can help companies implement a decentralized ownership pattern. A bus-based pattern using Amazon EventBridge can also be similarly utilized (see Figure 4).

Topic fanout pattern based on Amazon SQS and Amazon SNS

Figure 3. Topic fanout pattern based on Amazon SQS and Amazon SNS

Events bus pattern based on Amazon EventBridge

Figure 4. Events bus pattern based on Amazon EventBridge

The decentralized ownership approach has the advantage of promoting team independence, but it is not a fit for every organization. In order to be implemented effectively, a well-established DevOps culture is necessary. In this scenario, the producing teams are responsible for managing the message broker infrastructure and the non-functional requirements standards.

Centralized ownership

Ownership of the message broker in a centralized ownership organizational structure

Figure 5. Ownership of the message broker in a centralized ownership organizational structure

In a centralized ownership organizational structure, a central team (we’ll call it the platform team) is responsible for the management of the message broker (see Figure 5). Having a specialized platform team offers the advantage of standardized implementation of non-functional requirements, such as reliability, availability, and security. One disadvantage is that the platform team is a single point of failure in both the development and deployment lifecycle. This could become a bottleneck and put team independence and operational efficiency at risk.

Streaming pattern based on Amazon MSK and Kinesis Data Streams

Figure 6. Streaming pattern based on Amazon MSK and Kinesis Data Streams

On top of the implementation patterns mentioned in the previous section, the presence of a dedicated team makes it easier to implement streaming patterns. In this case, a deeper understanding on how the data is partitioned and how the system scales is required. Streaming patterns can be implemented using services such as Amazon Managed Streaming for Apache Kafka (MSK) or Amazon Kinesis Data Streams (see Figure 6).

Best practices for implementing event-driven architectures in your organization

The centralized and decentralized ownership organizational structures enhance team independence or standardization of non-functional requirements respectively. However, they introduce possible limits to the growth of the engineering function in a company. Inspired by the two approaches, you can implement a set of best practices which are aimed at minimizing those limitations.

Best practices for implementing event-driven architectures

Figure 7. Best practices for implementing event-driven architectures

  1. Introduce a cloud center of excellence (CCoE). A CCoE standardizes non-functional implementation across engineering teams. In order to promote a strong DevOps culture, the CCoE should not take the form of an external independent team, but rather be a collection of individual members representing the various engineering teams.
  2. Decentralize team ownership. Decentralize ownership and maintenance of the message broker to producing teams. This will maximize team independence and agility. It empowers the team to use the right tool for the right job, as long as they conform to the CCoE guidelines.
  3. Centralize logging standards and observability strategies. Although it is a best practice to decentralize team ownership of the components of an event-driven architecture, logging standards and observability strategies should be centralized and standardized across the engineering function. This centralization provides for end-to-end tracing of requests and events, which are powerful diagnosis tools in case of any failure.

Conclusion

In this post, we have described the main architectural components of an event-driven architecture, and identified the ownership of the message broker as one of the most important architectural choices you can make. We have described a centralized and decentralized organizational approach, presenting the strengths of the two approaches, as well as the limits they impose on the growth of your engineering organization. We have provided some best practices you can implement in your organization to minimize these limitations.

Further reading:
To start your journey building event-driven architectures in AWS, explore the following:

How to manage certificate lifecycles using ACM event-driven workflows

Post Syndicated from Shahna Campbell original https://aws.amazon.com/blogs/security/how-to-manage-certificate-lifecycles-using-acm-event-driven-workflows/

With AWS Certificate Manager (ACM), you can simplify certificate lifecycle management by using event-driven workflows to notify or take action on expiring TLS certificates in your organization. Using ACM, you can provision, manage, and deploy public and private TLS certificates for use with integrated AWS services like Amazon CloudFront and Elastic Load Balancing (ELB), as well as for your internal resources and infrastructure. For a full list of integrated services, see Services integrated with AWS Certificate Manager.

By implementing event-driven workflows for certificate lifecycle management, you can help increase the visibility of upcoming and actual certificate expirations, and notify application teams that their action is required to renew a certificate. You can also use event-driven workflows to automate provisioning of private certificates to your internal resources, like a web server based on Amazon Elastic Compute Cloud (Amazon EC2).

In this post, we describe the ACM event types that Amazon EventBridge supports. EventBridge is a serverless event router that you can use to build event-driven applications at scale. ACM publishes these events for important occurrences, such as when a certificate becomes available, approaches expiration, or fails to renew. We also highlight example use cases for the event types supported by ACM. Lastly, we show you how to implement an event-driven workflow to notify application teams that they need to take action to renew a certificate for their workloads. You can also use these types of workflows to send the relevant event information to AWS Security Hub or to initiate certificate automation actions through AWS Lambda.

To view a video walkthrough and demo of this workflow, see AWS Certificate Manager: How to create event-driven certificate workflows.

ACM event types and selected use cases

In October 2022, ACM released support for three new event types:

  • ACM Certificate Renewal Action Required
  • ACM Certificate Expired 
  • ACM Certificate Available

Before this release, ACM had a single event type: ACM Certificate Approaching Expiration. By default, ACM creates Certificate Approaching Expiration events daily for active, ACM-issued certificates starting 45 days prior to their expiration. To learn more about the structure of these event types, see Amazon EventBridge support for ACM. The following examples highlight how you can use the different event types in the context of certificate lifecycle operations.

Notify stakeholders that action is required to complete certificate renewal

ACM emits an ACM Certificate Renewal Action Required event when customer action must be taken before a certificate can be renewed. For instance, if permissions aren’t appropriately configured to allow ACM to renew private certificates issued from AWS Private Certificate Authority (AWS Private CA), ACM will publish this event when automatic renewal fails at 45 days before expiration. Similarly, ACM might not be able to renew a public certificate because an administrator needs to confirm the renewal by email validation, or because Certification Authority Authorization (CAA) record changes prevent automatic renewal through domain validation. ACM will make further renewal attempts at 30 days, 15 days, 3 days, and 1 day before expiration, or until customer action is taken, the certificate expires, or the certificate is no longer eligible for renewal. ACM publishes an event for each renewal attempt.

It’s important to notify the appropriate parties — for example, the Public Key Infrastructure (PKI) team, security engineers, or application developers — that they need to take action to resolve these issues. You might notify them by email, or by integrating with your workflow management system to open a case that the appropriate engineering or support teams can track.

Notify application teams that a certificate for their workload has expired

You can use the ACM Certificate Expired event type to notify application teams that a certificate associated with their workload has expired. The teams should quickly investigate and validate that the expired certificate won’t cause an outage or cause application users to see a message stating that a website is insecure, which could impact their trust. To increase visibility for support teams, you can publish this event to Security Hub or a support ticketing system. For an example of how to publish these events as findings in Security Hub, see Responding to an event with a Lambda function.

Use automation to export and place a renewed private certificate

ACM sends an ACM Certificate Available event when a managed public or private certificate is ready for use. ACM publishes the event on issuance, renewal, and import. When a private certificate becomes available, you might still need to take action to deploy it to your resources, such as installing the private certificate for use in an EC2 web server. This includes a new private certificate that AWS Private CA issues as part of managed renewal through ACM. You might want to notify the appropriate teams that the new certificate is available for export from ACM, so that they can use the ACM APIs, AWS Command Line Interface (AWS CLI), or AWS Management Console to export the certificate and manually distribute it to your workload (for example, an EC2-based web server). For integrated services such as ELB, ACM binds the renewed certificate to your resource, and no action is required.

You can also use this event to invoke a Lambda function that exports the private certificate and places it in the appropriate directory for the relevant server, provide it to other serverless resources, or put it in an encrypted Amazon Simple Storage Service (Amazon S3) bucket to share with a third party for mutual TLS or a similar use case.

How to build a workflow to notify administrators that action is required to renew a certificate

In this section, we’ll show you how to configure notifications to alert the appropriate stakeholders that they need to take an action to successfully renew an ACM certificate.

To follow along with this walkthrough, make sure that you have an AWS Identity and Access Management (IAM) role with the appropriate permissions for EventBridge and Amazon Simple Notification Service (Amazon SNS). When a rule runs in EventBridge, a target associated with that rule is invoked, and in order to make API calls on Amazon SNS, EventBridge needs a resource-based IAM policy.

The following IAM permissions work for the example below (and for tidying up afterwards):

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Action": [
        "events:*"
      ],
      "Effect": "Allow",
      "Resource": "arn:aws:events:*:*:*"
    },
    {
      "Action": [
        "iam:PassRole"
      ],
      "Effect": "Allow",
      "Resource": "*",
      "Condition": {
        "StringLike": {
          "iam:PassedToService": "events.amazonaws.com"
        }
      }
    }  
  ]
}

The following is a sample resource-based policy that allows EventBridge to publish to an Amazon SNS topic. Make sure to replace <region>, <account-id>, and <topic-name> with your own data.

{
  "Sid": "PublishEventsToMyTopic",
  "Effect": "Allow",
  "Principal": {
    "Service": "events.amazonaws.com"
  },
  "Action": "sns:Publish",
  "Resource": "arn:aws:sns:<region>:<account-id>:<topic-name>"
}

The first step is to create an SNS topic by using the console to link multiple endpoints such as AWS Lambda and Amazon Simple Queue Service (Amazon SQS), or send a notification to an email address.

To create an SNS topic

  1. Open the Amazon SNS console.
  2. In the left navigation pane, choose Topics.
  3. Choose Create Topic.
  4. For Type, choose Standard.
  5. Enter a name for the topic, and (optional) enter a display name.
  6. Choose the triangle next to the Encryption — optional panel title.
    1. Select the Encryption toggle (optional) to encrypt the topic. This will enable server-side encryption (SSE) to help protect the contents of the messages in Amazon SNS topics.
    2. For this demonstration, we are going to use the default AWS managed KMS key. Using Amazon SNS with AWS Key Management Service (AWS KMS) provides encryption at rest, and the data keys that encrypt the SNS message data are stored with the data protected. To learn more about SNS data encryption, see Data encryption.
  7. Keep the defaults for all other settings.
  8. Choose Create topic.

When the topic has been successfully created, a notification bar appears at the top of the screen, and you will be routed to the page for the newly created topic. Note the Amazon Resource Name (ARN) listed in the Details panel because you’ll need it for the next section.

Next, you need to create a subscription to the topic to set a destination endpoint for the messages that are pushed to the topic to be delivered.

To create a subscription to the topic

  1. In the Subscriptions section of the SNS topic page you just created, choose Create subscription.
  2. On the Create subscription page, in the Details section, do the following:
    1. For Protocol, choose Email.
    2. For Endpoint, enter the email address where the ACM Certificate Renewal Action Required event alerts should be sent.
    3. Keep the default Subscription filter policy and Redrive policy settings for this demonstration.
    4. Choose Create subscription.
  3. To finalize the subscription, an email will be sent to the email address that you entered as the endpoint. To validate your subscription, choose Confirm Subscription in the email when you receive it.
  4. A new web browser will open with a message verifying that the subscription status is Confirmed and that you have been successfully subscribed to the SNS topic.

Next, create the EventBridge rule that will be invoked when an ACM Certificate Renewal Action Required event occurs. This rule uses the SNS topic that you just created as a target.

To create an EventBridge rule

  1. Navigate to the EventBridge console.
  2. In the left navigation pane, choose Rules.
  3. Choose Create rule.
  4. In the Rule detail section, do the following:
    1. Define the rule by entering a Name and an optional Description.
    2. In the Event bus dropdown menu, select the default event bus.
    3. Keep the default values for the rest of the settings.
    4. Choose Next.
  5. For Event source, make sure that AWS events or EventBridge partner events is selected, because the event source is ACM.
  6. In the Sample event panel, under Sample events, choose ACM Certificate Renewal Action Required as the sample event. This helps you verify your event pattern.
  7. In the Event pattern panel, for Event Source, make sure that AWS services is selected. 
  8. For AWS service, choose Certificate Manager.
  9. Under Event type, choose ACM Certificate Renewal Action Required.
  10. Choose Test pattern.
  11. In the Event pattern section, a notification will appear stating Sample event matched the event pattern to confirm that the correct event pattern was created.
  12. Choose Next.
  13. In the Target 1 panel, do the following:
    1. For Target types, make sure that AWS service is selected.
    2. Under Select a target, choose SNS topic.
    3. In the Topic dropdown list, choose your desired topic.
    4. Choose Next.
  14. (Optional) Add tags to the topic.
  15. Choose Next.
  16. Review the settings for the rule, and then choose Create rule.

Now you are listening to this event and will be notified when a customer action must be taken before a certificate can be renewed.

For another example of how to use Amazon SNS and email notifications, see How to monitor expirations of imported certificates in AWS Certificate Manager (ACM). For an example of how to use Lambda to publish findings to Security Hub to provide visibility to administrators and security teams, see Responding to an event with a Lambda function. Other options for responding to this event include invoking a Lambda function to export and distribute private certificates, or integrating with a messaging or collaboration tool for ChatOps.

Conclusion 

In this blog post, you learned about the new EventBridge event types for ACM, and some example use cases for each of these event types. You also learned how to use these event types to create a workflow with EventBridge and Amazon SNS that notifies the appropriate stakeholders when they need to take action, so that ACM can automatically renew a TLS certificate.

By using these events to increase awareness of upcoming certificate lifecycle events, you can make it simpler to manage TLS certificates across your organization. For more information about certificate management on AWS, see the ACM documentation or get started using ACM today in the AWS Management Console.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Shahna Campbell

Shahna Campbell

Shahna is a solutions architect at AWS, working within the specialist organization with a focus on security. Previously, Shahna worked within the healthcare field clinically and as an application specialist. Shahna is passionate about cybersecurity and analytics. In her free time she enjoys hiking, traveling, and spending time with family.

Mani Subramanian

Manikandan Subramanian

Manikandan is a principal engineer at AWS Cryptography. His primary focus is on public key infrastructure (PKI), and he helps ensure secure communication using TLS certificates for AWS customers. Mani is also passionate at designing APIs, is an API bar raiser, and has helped launch multiple AWS services. Outside of work, Mani enjoys cooking and watching Formula One.

Zach Miller

Zach Miller

Zach is a Senior Security Specialist Solutions Architect at AWS. His background is in data protection and security architecture, focused on a variety of security domains, including cryptography, secrets management, and data classification. Today, he is focused on helping enterprise AWS customers adopt and operationalize AWS security services to increase security effectiveness and reduce risk.

Decoupling event publishing with Amazon EventBridge Pipes

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/decoupling-event-publishing-with-amazon-eventbridge-pipes/

This post is written by Gregor Hohpe, Sr. Principal Evangelist, Serverless.

Event-driven architectures (EDAs) help decouple applications or application components from one another. Consuming events makes a component less dependent on the sender’s location or implementation details. Because events are self-contained, they can be consumed asynchronously, which allows sender and receiver to follow independent timing considerations. Decoupling through events can improve development agility and operational resilience when building fine-grained distributed applications, which is the preferred style for serverless applications.

Many AWS services publish events through built-in mechanisms to support building event-driven architectures with a minimal amount of custom coding. Modern applications built on top of those services can also send and consume events based on their specific business logic. AWS application integration services like Amazon EventBridge or Amazon SNS, a managed publish-subscribe service, filter those events and route them to the intended destination, providing additional decoupling between event producer and consumer.

Publishing events

Custom applications that act as event producers often use the AWS SDK library, which is available for 12 programming languages, to send an event message. The application code constructs the event as a local data structure and specifies where to send it, for example to an EventBridge event bus.

The application code required to send an event to EventBridge is straightforward and only requires a few lines of code, as shown in this (simplified) helper method that publishes an order event generated by the application:

async function sendEvent(event) {
    const ebClient = new EventBridgeClient();
    const params = { Entries: [ {
          Detail: JSON.stringify(event),
          DetailType: "newOrder",
          Source: "orders",
          EventBusName: eventBusName
        } ] };
    return await ebClient.send(new PutEventsCommand(params));
}

An application most likely calls such a method in the context of another action, for example when persisting a received order to a data store. The code that performs those tasks might look as follows:

const order = { "orderId": "1234", "Items": ["One", "Two", "Three"] }
await writeToDb(order);
await sendEvent(order);

The code populates an order object with multiple line items (in reality, this would be based on data entered by a user or received via an API call), writes it to a database (via another helper method whose implementation isn’t shown), and then sends it to an EventBridge bus via the preceding method.

Code causes coupling

Although this code is not complex, it has drawbacks from an architectural perspective:

  • It interweaves application logic with the solution’s topology because the destination of the event, both in terms of service (EventBridge versus SNS, for example) and the instance (the service bus name in this case) are defined inside the application’s source code. If the event destination changes, you must change the source code, or at least know which string constant is passed to the function via an environment variable. Both aspects work against the EDA principle of minimizing coupling between components because changes in the communication structure propagate into the producer’s source code.
  • Sending the event after updating the database is brittle because it lacks transactional guarantees across both steps. You must implement error handling and retry logic to handle cases where sending the event fails, or even undo the database update. Writing such code can be tedious and error-prone.
  • Code is a liability. After all, that’s where bugs come from. In a real-life example, a helper method similar to preceding code erroneously swapped day and month on the event date, which led to a challenging debugging cycle. Boilerplate code to send events is therefore best avoided.

Performing event routing inside EventBridge can lessen the first concern. You could reconfigure EventBridge’s rules and targets to route events with a specified type and source to a different destination, provided you keep the event bus name stable. However, the other issues would remain.

Serverless: Less infrastructure, less code

AWS serverless integration services can alleviate the need to write custom application code to publish events altogether.

A key benefit of serverless applications is that you can let the AWS Cloud do the undifferentiated heavy lifting for you. Traditionally, we associate serverless with provisioning, scaling, and operating compute infrastructure so that developers can focus on writing code that generates business value.

Serverless application integration services can also take care of application-level tasks for you, including publishing events. Most applications store data in AWS data stores like Amazon Simple Storage Service (S3) or Amazon DynamoDB, which can automatically emit events whenever an update takes place, without any application code.

EventBridge Pipes: Events without application code

EventBridge Pipes allows you to create point-to-point integrations between event producers and consumers with optional transformation, filtering, and enrichment steps. Serverless integration services combined with cloud automation allow ”point-to-point” integrations to be more easily managed than in the past, which makes them a great fit for this use case.

This example takes advantage of EventBridge Pipes’ ability to fetch events actively from sources like DynamoDB Streams. DynamoDB Streams captures a time-ordered sequence of item-level modifications in any DynamoDB table and stores this information in a log for up to 24 hours. EventBridge Pipes picks up events from that log and pushes them to one of over 14 event targets, including an EventBridge bus, SNS, SQS, or API Destinations. It also accommodates batch sizes, timeouts, and rate limiting where needed.

EventBridge Pipes example

The integration through EventBridge Pipes can replace the custom application code that sends the event, including any retry or error logic. Only the following code remains:

const order = { "orderId": "1234", "Items": ["One", "Two", "Three"] }
await writeToDb(order);

Automation as code

EventBridge Pipes can be configured from the CLI, the AWS Management Console, or from automation code using AWS CloudFormation or AWS CDK. By using AWS CDK, you can use the same programming language that you use to write your application logic to also write your automation code.

For example, the following CDK snippet configures an EventBridge Pipe to read events from a DynamoDB Stream attached to the Orders table and passes them to an EventBridge event bus.

This code references the DynamoDB table via the ordersTable variable that would be set when the table is created:

const pipe = new CfnPipe(this, 'pipe', {
  roleArn: pipeRole.roleArn,
  source: ordersTable.tableStreamArn!,
  sourceParameters: {
    dynamoDbStreamParameters: {
      startingPosition: 'LATEST'
    },
  },
  target: ordersEventBus.eventBusArn,
  targetParameters: {
    eventBridgeEventBusParameters: {
      detailType: 'order-details',
      source: 'my-source',
    },
  },
}); 

The automation code cleanly defines the dependency between the DynamoDB table and the event destination, independent of application logic.

Decoupling with data transformation

Coupling is not limited to event sources and destinations. A source’s data format can determine the event format and require downstream changes in case the data format or the data source change. EventBridge Pipes can also alleviate that consideration.

Events emitted from the DynamoDB Stream use the native, marshaled DynamoDB format that includes type information, such as an “S” for strings or “L” for lists.

For example, the order event in the DynamoDB stream from this example looks as follows. Some fields are omitted for readability:

{
  "detail": {
    "eventID": "be1234f372dd12552323a2a3362f6bd2",
    "eventName": "INSERT",
    "eventSource": "aws:dynamodb",
    "dynamodb": {
      "Keys": { "orderId": { "S": "ABCDE" } },
      "NewImage": { 
        "orderId": { "S": "ABCDE" },
        "items": {
            "L": [ { "S": "One" }, { "S": "Two" }, { "S": "Three" } ]
        }
      }
    }
  }
} 

This format is not well suited for downstream processing because it would unnecessarily couple event consumers to the fact that this event originated from a DynamoDB Stream. EventBridge Pipes can convert this event into a more easily consumable format. The transformation is specified via an inputTemplate parameter using JSONPath expressions. EventBridge Pipes added support for list processing with wildcards proves to be perfect for this scenario.

In this example, add the following transformation template inside the target parameters to the preceding CDK code (the asterisk character matches a complete list of elements):

targetParameters: {
  inputTemplate: '{"orderId": <$.dynamodb.NewImage.orderId.S>,' + 
                 '"items": <$.dynamodb.NewImage.items.L[*].S>}'
}

This transformation formats the event published by EventBridge Pipes like a regular business event, decoupling any event consumer from the fact that it originated from a DynamoDB table:

{
  "time": "2023-06-01T06:18:10Z",
  "detail": {
    "orderId": "ABCDE",
    "items": ["One", "Two", "Three" ]
  }
}

Conclusion

When building event-driven applications, consider whether you can replace application code with serverless integration services to improve the resilience of your application and provide a clean separation between application logic and system dependencies.

EventBridge Pipes can be a helpful feature in these situations, for example to capture and publish events based on DynamoDB table updates.

Learn more about EventBridge Pipes at https://aws.amazon.com/eventbridge/pipes/ and discover additional ways to reduce serverless application code at https://serverlessland.com/refactoring-serverless. For a complete code example, see https://github.com/aws-samples/aws-refactoring-to-serverless.

Implementing AWS Lambda error handling patterns

Post Syndicated from Julian Wood original https://aws.amazon.com/blogs/compute/implementing-aws-lambda-error-handling-patterns/

This post is written by Jeff Chen, Principal Cloud Application Architect, and Jeff Li, Senior Cloud Application Architect

Event-driven architectures are an architecture style that can help you boost agility and build reliable, scalable applications. Splitting an application into loosely coupled services can help each service scale independently. A distributed, loosely coupled application depends on events to communicate application change states. Each service consumes events from other services and emits events to notify other services of state changes.

Handling errors becomes even more important when designing distributed applications. A service may fail if it cannot handle an invalid payload, dependent resources may be unavailable, or the service may time out. There may be permission errors that can cause failures. AWS services provide many features to handle error conditions, which you can use to improve the resiliency of your applications.

This post explores three use-cases and design patterns for handling failures.

Overview

AWS Lambda, Amazon Simple Queue Service (Amazon SQS), Amazon Simple Notification Service (Amazon SNS), and Amazon EventBridge are core building blocks for building serverless event-driven applications.

The post Understanding the Different Ways to Invoke Lambda Functions lists the three different ways of invoking a Lambda function: synchronous, asynchronous, and poll-based invocation. For a list of services and which invocation method they use, see the documentation.

Lambda’s integration with Amazon API Gateway is an example of a synchronous invocation. A client makes a request to API Gateway, which sends the request to Lambda. API Gateway waits for the function response and returns the response to the client. There are no built-in retries or error handling. If the request fails, the client attempts the request again.

Lambda’s integration with SNS and EventBridge are examples of asynchronous invocations. SNS, for example, sends an event to Lambda for processing. When Lambda receives the event, it places it on an internal event queue and returns an acknowledgment to SNS that it has received the message. Another Lambda process reads events from the internal queue and invokes your Lambda function. If SNS cannot deliver an event to your Lambda function, the service automatically retries the same operation based on a retry policy.

Lambda’s integration with SQS uses poll-based invocations. Lambda runs a fleet of pollers that poll your SQS queue for messages. The pollers read the messages in batches and invoke your Lambda function once per batch.

You can apply this pattern in many scenarios. For example, your operational application can add sales orders to an operational data store. You may then want to load the sales orders to your data warehouse periodically so that the information is available for forecasting and analysis. The operational application can batch completed sales as events and place them on an SQS queue. A Lambda function can then process the events and load the completed sale records into your data warehouse.

If your function processes the batch successfully, the pollers delete the messages from the SQS queue. If the batch is not successfully processed, the pollers do not delete the messages from the queue. Once the visibility timeout expires, the messages are available again to be reprocessed. If the message retention period expires, SQS deletes the message from the queue.

The following table shows the invocation types and retry behavior of the AWS services mentioned.

AWS service example Invocation type Retry behavior
Amazon API Gateway Synchronous No built-in retry, client attempts retries.

Amazon SNS

Amazon EventBridge

Asynchronous Built-in retries with exponential backoff.
Amazon SQS Poll-based Retries after visibility timeout expires until message retention period expires.

There are a number of design patterns to use for poll-based and asynchronous invocation types to retain failed messages for additional processing. These patterns can help you recover from delivery or processing failures.

You can explore the patterns and test the scenarios by deploying the code from this repository which uses the AWS Cloud Development Kit (AWS CDK) using Python.

Lambda poll-based invocation pattern

When using Lambda with SQS, if Lambda isn’t able to process the message and the message retention period expires, SQS drops the message. Failure to process the message can be due to function processing failures, including time-outs or invalid payloads. Processing failures can also occur when the destination function does not exist, or has incorrect permissions.

You can configure a separate dead-letter queue (DLQ) on the source queue for SQS to retain the dropped message. A DLQ preserves the original message and is useful for analyzing root causes, handling error conditions properly, or sending notifications that require manual interventions. In the poll-based invocation scenario, the Lambda function itself does not maintain a DLQ. It relies on the external DLQ configured in SQS. For more information, see Using Lambda with Amazon SQS.

The following shows the design pattern when you configure Lambda to poll events from an SQS queue and invoke a Lambda function.

Lambda synchronously polling catches of messages from SQS

Lambda synchronously polling batches of messages from SQS

To explore this pattern, deploy the code in this repository. Once deployed, you can use this instruction to test the pattern with the happy and unhappy paths.

Lambda asynchronous invocation pattern

With asynchronous invokes, there are two failure aspects to consider when using Lambda. The event source cannot deliver the message to Lambda and the Lambda function errors when processing the event.

Event sources vary in how they handle failures delivering messages to Lambda. If SNS or EventBridge cannot send the event to Lambda after exhausting all their retry attempts, the service drops the event. You can configure a DLQ on an SNS topic or EventBridge event bus to hold the dropped event. This works in the same way as the poll-based invocation pattern with SQS.

Lambda functions may then error due to input payload syntax errors, duration time-outs, or the function throws an exception such as a data resource not available.

For asynchronous invokes, you can configure how long Lambda retains an event in its internal queue, up to 6 hours. You can also configure how many times Lambda retries when the function errors, between 0 and 2. Lambda discards the event when the maximum age passes or all retry attempts fail. To retain a copy of discarded events, you can configure either a DLQ or, preferably, a failed-event destination as part of your Lambda function configuration.

A Lambda destination enables you to specify what to do next if an asynchronous invocation succeeds or fails. You can configure a destination to send invocation records to SQS, SNS, EventBridge, or another Lambda function. Destinations are preferred for failure processing as they support additional targets and include additional information. A DLQ holds the original failed event. With a destination, Lambda also passes details of the function’s response in the invocation record. This includes stack traces, which can be useful for analyzing the root cause.

Using both a DLQ and Lambda destinations

You can apply this pattern in many scenarios. For example, many of your applications may contain customer records. To comply with the California Consumer Privacy Act (CCPA), different organizations may need to delete records for a particular customer. You can set up a consumer delete SNS topic. Each organization creates a Lambda function, which processes the events published by the SNS topic and deletes customer records in its managed applications.

The following shows the design pattern when you configure an SNS topic as the event source for a Lambda function, which uses destination queues for success and failure process.

SNS topic as event source for Lambda

SNS topic as event source for Lambda

You configure a DLQ on the SNS topic to capture messages that SNS cannot deliver to Lambda. When Lambda invokes the function, it sends details of the successfully processed messages to an on-success SQS destination. You can use this pattern to route an event to multiple services for simpler use cases. For orchestrating multiple services, AWS Step Functions is a better design choice.

Lambda can also send details of unsuccessfully processed messages to an on-failure SQS destination.

A variant of this pattern is to replace an SQS destination with an EventBridge destination so that multiple consumers can process an event based on the destination.

To explore how to use an SQS DLQ and Lambda destinations, deploy the code in this repository. Once deployed, you can use this instruction to test the pattern with the happy and unhappy paths.

Using a DLQ

Although destinations is the preferred method to handle function failures, you can explore using DLQs.

The following shows the design pattern when you configure an SNS topic as the event source for a Lambda function, which uses SQS queues for failure process.

Lambda invoked asynchonously

Lambda invoked asynchonously

You configure a DLQ on the SNS topic to capture the messages that SNS cannot deliver to the Lambda function. You also configure a separate DLQ for the Lambda function. Lambda saves an unsuccessful event to this DLQ after Lambda cannot process the event after maximum retry attempts.

To explore how to use a Lambda DLQ, deploy the code in this repository. Once deployed, you can use this instruction to test the pattern with happy and unhappy paths.

Conclusion

This post explains three patterns that you can use to design resilient event-driven serverless applications. Error handling during event processing is an important part of designing serverless cloud applications.

You can deploy the code from the repository to explore how to use poll-based and asynchronous invocations. See how poll-based invocations can send failed messages to a DLQ. See how to use DLQs and Lambda destinations to route and handle unsuccessful events.

Learn more about event-driven architecture on Serverless Land.

Serverless ICYMI Q2 2023

Post Syndicated from Benjamin Smith original https://aws.amazon.com/blogs/compute/serverless-icymi-q2-2023/

Welcome to the 22nd edition of the AWS Serverless ICYMI (in case you missed it) quarterly recap. Every quarter, we share all the most recent product launches, feature enhancements, blog posts, webinars, live streams, and other interesting things that you might have missed!

In case you missed our last ICYMI, check out what happened last quarter here.

Serverless Innovation Day

AWS recently hosted the Serverless Innovation Day, a day of live streams that showcased AWS serverless technologies such as AWS Lambda, Amazon ECS with AWS Fargate, Amazon EventBridge, and AWS Step Functions. The event included insights from AWS leaders such as Holly Mesrobian, Ajay Nair, and Usman Khalid, as well as prominent customers and our serverless Developer Advocate team. It provided insights into serverless modernization success stories, use cases, and best practices. If you missed the event, you can catch up on the recorded sessions here.

Serverless Land, your go-to resource for all things serverless, expanded to include a new Serverless Testing section. This provides valuable insights, patterns, and best practices for testing integrations using AWS SAM and CDK templates.

Serverless Land also launched a new learning page featuring a collection of resources, including blog posts, videos, workshops, and training materials, allowing users to choose a learning path from a variety of topics. “EventBridge Visuals“, small, easily digestible visuals focused on EventBridge have also been added.

AWS Lambda

Lambda introduced support for response payload streaming allowing functions to progressively stream response data to clients. This feature significantly improves performance by reducing the time to first byte (TTFB) latency, benefiting web and mobile applications.

Response streaming is particularly useful for applications with large payloads such as images, videos, documents, or database results. It eliminates the need to buffer the entire payload in memory and enables the transfer of responses larger than Lambda’s 6 MB limit, up to a soft limit of 20 MB.

By configuring the Function URL to use the InvokeWithResponseStream API, streaming responses can be accessed through an HTTP client that supports incremental response data. This enhancement expands Lambda’s capabilities, allowing developers to handle larger payloads more efficiently and enhance the overall performance and user experience of their web and mobile applications.

Lambda now supports Java 17 with Amazon Corretto distribution, providing long-term support and improved performance. Java 17 introduces new language features like records, sealed classes, and multi-line strings. The runtime uses ZGC and Shenandoah garbage collectors to reduce latency. Default JVM configuration changes optimize tiered compilation for reduced startup latency. Developers can use Java 17 in Lambda through AWS Management Console, AWS SAM, and AWS CDK. Popular frameworks like Spring Boot 3 and Micronaut 4 require Java 17 as a minimum. Micronaut provides a web service to generate example projects using Java 17 and AWS CDK infrastructure.

Lambda now supports the Ruby 3.2 runtime, enabling you to write serverless functions using the latest version of the Ruby programming language. This update enhances developer productivity and brings new features and improvements to your Ruby-based Lambda functions.

Lambda introduced support for Kafka and Amazon MQ event sources in four additional Regions. This expanded availability allows developers to build event-driven architectures using these messaging systems in more regions around the world, providing greater flexibility and scalability. It also supports Kafka and Amazon MQ event sources in AWS GovCloud (US) Regions, allowing government organizations to leverage the benefits of event-driven architectures in their cloud environments.

Lambda also added support for starting from a specific timestamp for Kafka event sources, allowing for precise message processing and useful scenarios like Disaster Recovery, without any additional charges.

Serverless Land has launched new learning paths for Lambda to help you level up your serverless skills:

  • The Java Replatforming learning path guides Java developers through the process of migrating existing Java applications to a serverless architecture.
  • The Lift and Shift to Serverless learning path provides guidance on migrating traditional applications to a serverless environment.
  • Lambda Fundamentals is a 23-part video series providing practical examples and tips to help you get started with serverless development using Lambda.

The new AWS Tech Talk, Best practices for building interactive applications with AWS Lambda, helps you learn best practices and architectural patterns for building web and mobile backends as well as API-driven microservices on Lambda. Explore how to take advantage of features in Lambda, Amazon API Gateway, Amazon DynamoDB, and more to easily build highly scalable serverless web applications.

AWS Step Functions

The latest update to AWS Step Functions introduces versions and aliases, allows users to run specific state machine revisions, ensuring reliable deployments, reducing risks, and providing version visibility. Appending version numbers to the state machine ARN enables selection of desired versions, even after updates. Aliases distribute execution requests based on weights, supporting incremental deployment patterns.

This enhances confidence in state machine updates, improves observability, auditing, and can be managed through the Step Functions console or AWS CloudFormation. Versions and aliases are available in all supported AWS Regions at no extra cost.

AWS SAM

AWS SAM CLI has introduced a new feature called remote invoke that allows developers to test Lambda functions in the AWS Cloud. This feature enables developers to invoke Lambda functions from their local development environment and provides options for event payloads, output formats, and logging.

It can be used with or without AWS SAM and can be combined with AWS SAM Accelerate for streamlined development and testing. Overall, the remote invoke feature simplifies serverless application testing in the AWS Cloud.

Amazon EventBridge

EventBridge announced an open-source connector for Kafka Connect, providing seamless integration between EventBridge and Kafka Connect. This connector simplifies the process of streaming events from Kafka topics to EventBridge, enabling you to build event-driven architectures with ease.

EventBridge has improved end-to-end latencies for event buses, delivering events up to 80% faster. This enables broader use in latency-sensitive applications such as industrial and medical applications, with the lower latencies applied by default across all AWS Regions at no extra cost.

Amazon Aurora Serverless v2

Amazon Aurora Serverless v2 is now available in four additional Regions, expanding the reach of this scalable and cost-effective serverless database option. With Aurora Serverless v2, you can benefit from automatic scaling, pause-and-resume capability, and pay-per-use pricing, enabling you to optimize costs and manage your databases more efficiently.

Amazon SNS

Amazon SNS now supports message data protection in five additional Regions, ensuring the security and integrity of your message payloads. With this feature, you can encrypt sensitive message data at rest and in transit, meeting compliance requirements and safeguarding your data.

Serverless Blog Posts

April 2023

Apr 27 – AWS Lambda now supports Java 17

Apr 27 – Optimizing Amazon EC2 Spot Instances with Spot Placement Scores

Apr 26 – Building private serverless APIs with AWS Lambda and Amazon VPC Lattice

Apr 25 – Implementing error handling for AWS Lambda asynchronous invocations

Apr 20 – Understanding techniques to reduce AWS Lambda costs in serverless applications

Apr 18 – Python 3.10 runtime now available in AWS Lambda

Apr 13 – Optimizing AWS Lambda extensions in C# and Rust

Apr 7 – Introducing AWS Lambda response streaming

May 2023

May 24 – Developing a serverless Slack app using AWS Step Functions and AWS Lambda

May 11 – Automating stopping and starting Amazon MWAA environments to reduce cost

May 10 – Monitor Amazon SNS-based applications end-to-end with AWS X-Ray active tracing

May 10 – Debugging SnapStart-enabled Lambda functions made easy with AWS X-Ray

May 10 – Implementing cross-account CI/CD with AWS SAM for container-based Lambda functions

May 3 – Extending a serverless, event-driven architecture to existing container workloads

May 3 – Patterns for building an API to upload files to Amazon S3

June 2023

Jun 7 – Ruby 3.2 runtime now available in AWS Lambda

Jun 5 – Implementing custom domain names for Amazon API Gateway private endpoints using a reverse proxy

June 22 – Deploying state machines incrementally with versions and aliases in AWS Step Functions

June 22 – Testing AWS Lambda functions with AWS SAM remote invoke

Videos

Serverless Office Hours – Tues 10AM PT

Weekly live virtual office hours. In each session we talk about a specific topic or technology related to serverless and open it up to helping you with your real serverless challenges and issues.

YouTube: youtube.com/serverlessland
Twitch: twitch.tv/aws

LinkedIn:  linkedin.com/company/serverlessland

April 2023

Apr 4 – Serverless AI with ChatGPT and DALL-E

Apr 11 – Building Java apps with AWS SAM

Apr 18 – Managing EventBridge with Kubernetes

Apr 25 – Lambda response streaming

May 2023

May 2 – Automating your life with serverless 

May 9 – Building real-life asynchronous architectures

May 16 – Testing Serverless Applications

May 23 – Build faster with Amazon CodeCatalyst 

May 30 – Serverless networking with VPC Lattice

June 2023

June 6 – AWS AppSync: Private APIs and Merged APIs 

June 13 – Integrating EventBridge and Kafka

June 20 – AWS Copilot for serverless containers

June 27 – Serverless high performance modeling

FooBar Serverless YouTube channel

April 2023

Apr 6 – Designing a DynamoDB Table in 4 Steps: From Entities to Access Patterns

Apr 14 – Amazon CodeWhisperer – Improve developer productivity using machine learning (ML)

Apr 20 – Beginner’s Guide to DynamoDB with AWS CDK: Step-by-Step Tutorial for provisioning NoSQL Databases

Apr 27 – Build a WebApp that uses DynamoDB in 6 steps | DynamoDB Expressions

May 2023

May 4 – How to Migrate Data to DynamoDB?

May 11 – Load Testing DynamoDB: Observability and Performance tuning

May 18 – DynamoDB Streams – THE most powerful feature from DynamoDB for event-driven applications

May 25 – Track Application Events with DynamoDB streams and Email Notifications using EventBridge Pipes

June 2023

Jun 1 – How to filter messages based on the payload using Amazon SNS

June 8 – Getting started with Amazon Kinesis

Still looking for more?

The Serverless landing page has more information. The Lambda resources page contains case studies, webinars, whitepapers, customer stories, reference architectures, and even more Getting Started tutorials.

You can also follow the Serverless Developer Advocacy team on Twitter to see the latest news, follow conversations, and interact with the team.

Three ways to accelerate incident response in the cloud: insights from re:Inforce 2023

Post Syndicated from Anne Grahn original https://aws.amazon.com/blogs/security/three-ways-to-accelerate-incident-response-in-the-cloud-insights-from-reinforce-2023/

AWS re:Inforce took place in Anaheim, California, on June 13–14, 2023. AWS customers, partners, and industry peers participated in hundreds of technical and non-technical security-focused sessions across six tracks, an Expo featuring AWS experts and AWS Security Competency Partners, and keynote and leadership sessions.

The threat detection and incident response track showcased how AWS customers can get the visibility they need to help improve their security posture, identify issues before they impact business, and investigate and respond quickly to security incidents across their environment.

With dozens of service and feature announcements—and innumerable best practices shared by AWS experts, customers, and partners—distilling highlights is a challenge. From an incident response perspective, three key themes emerged.

Proactively detect, contextualize, and visualize security events

When it comes to effectively responding to security events, rapid detection is key. Among the launches announced during the keynote was the expansion of Amazon Detective finding groups to include Amazon Inspector findings in addition to Amazon GuardDuty findings.

Detective, GuardDuty, and Inspector are part of a broad set of fully managed AWS security services that help you identify potential security risks, so that you can respond quickly and confidently.

Using machine learning, Detective finding groups can help you conduct faster investigations, identify the root cause of events, and map to the MITRE ATT&CK framework to quickly run security issues to ground. The finding group visualization panel shown in the following figure displays findings and entities involved in a finding group. This interactive visualization can help you analyze, understand, and triage the impact of finding groups.

Figure 1: Detective finding groups visualization panel

Figure 1: Detective finding groups visualization panel

With the expanded threat and vulnerability findings announced at re:Inforce, you can prioritize where to focus your time by answering questions such as “was this EC2 instance compromised because of a software vulnerability?” or “did this GuardDuty finding occur because of unintended network exposure?”

In the session Streamline security analysis with Amazon Detective, AWS Principal Product Manager Rich Vorwaller, AWS Senior Security Engineer Rima Tanash, and AWS Program Manager Jordan Kramer demonstrated how to use graph analysis techniques and machine learning in Detective to identify related findings and resources, and investigate them together to accelerate incident analysis.

In addition to Detective, you can also use Amazon Security Lake to contextualize and visualize security events. Security Lake became generally available on May 30, 2023, and several re:Inforce sessions focused on how you can use this new service to assist with investigations and incident response.

As detailed in the following figure, Security Lake automatically centralizes security data from AWS environments, SaaS providers, on-premises environments, and cloud sources into a purpose-built data lake stored in your account. Security Lake makes it simpler to analyze security data, gain a more comprehensive understanding of security across an entire organization, and improve the protection of workloads, applications, and data. Security Lake automates the collection and management of security data from multiple accounts and AWS Regions, so you can use your preferred analytics tools while retaining complete control and ownership over your security data. Security Lake has adopted the Open Cybersecurity Schema Framework (OCSF), an open standard. With OCSF support, the service normalizes and combines security data from AWS and a broad range of enterprise security data sources.

Figure 2: How Security Lake works

Figure 2: How Security Lake works

To date, 57 AWS security partners have announced integrations with Security Lake, and we now have more than 70 third-party sources, 16 analytics subscribers, and 13 service partners.

In Gaining insights from Amazon Security Lake, AWS Principal Solutions Architect Mark Keating and AWS Security Engineering Manager Keith Gilbert detailed how to get the most out of Security Lake. Addressing questions such as, “How do I get access to the data?” and “What tools can I use?,” they demonstrated how analytics services and security information and event management (SIEM) solutions can connect to and use data stored within Security Lake to investigate security events and identify trends across an organization. They emphasized how bringing together logs in multiple formats and normalizing them into a single format empowers security teams to gain valuable context from security data, and more effectively respond to events. Data can be queried with Amazon Athena, or pulled by Amazon OpenSearch Service or your SIEM system directly from Security Lake.

Build your security data lake with Amazon Security Lake featured AWS Product Manager Jonathan Garzon, AWS Product Solutions Architect Ross Warren, and Global CISO of Interpublic Group (IPG) Troy Wilkinson demonstrating how Security Lake helps address common challenges associated with analyzing enterprise security data, and detailing how IPG is using the service. Wilkinson noted that IPG’s objective is to bring security data together in one place, improve searches, and gain insights from their data that they haven’t been able to before.

“With Security Lake, we found that it was super simple to bring data in. Not just the third-party data and Amazon data, but also our on-premises data from custom apps that we built.” — Troy Wilkinson, global CISO, Interpublic Group

Use automation and machine learning to reduce mean time to response

Incident response automation can help free security analysts from repetitive tasks, so they can spend their time identifying and addressing high-priority security issues.

In How LLA reduces incident response time with AWS Systems Manager, telecommunications provider Liberty Latin America (LLA) detailed how they implemented a security framework to detect security issues and automate incident response in more than 180 AWS accounts accessed by internal stakeholders and third-party partners by using AWS Systems Manager Incident Manager, AWS Organizations, Amazon GuardDuty, and AWS Security Hub.

LLA operates in over 20 countries across Latin America and the Caribbean. After completing multiple acquisitions, LLA needed a centralized security operations team to handle incidents and notify the teams responsible for each AWS account. They used GuardDuty, Security Hub, and Systems Manager Incident Manager to automate and streamline detection and response, and they configured the services to initiate alerts whenever there was an issue requiring attention.

Speaking alongside AWS Principal Solutions Architect Jesus Federico and AWS Principal Product Manager Sarah Holberg, LLA Senior Manager of Cloud Services Joaquin Cameselle noted that when GuardDuty identifies a critical issue, it generates a new finding in Security Hub. This finding is then forwarded to Systems Manager Incident Manager through an Amazon EventBridge rule. This configuration helps ensure the involvement of the appropriate individuals associated with each account.

“We have deployed a security framework in Liberty Latin America to identify security issues and streamline incident response across over 180 AWS accounts. The framework that leverages AWS Systems Manager Incident Manager, Amazon GuardDuty, and AWS Security Hub enabled us to detect and respond to incidents with greater efficiency. As a result, we have reduced our reaction time by 90%, ensuring prompt engagement of the appropriate teams for each AWS account and facilitating visibility of issues for the central security team.” — Joaquin Cameselle, senior manager, cloud services, Liberty Latin America

How Citibank (Citi) advanced their containment capabilities through automation outlined how the National Institute of Standards and Technology (NIST) Incident Response framework is applied to AWS services, and highlighted Citi’s implementation of a highly scalable cloud incident response framework designed to support the 28 AWS services in their cloud environment.

After describing the four phases of the incident response process — preparation and prevention; detection and analysis; containment, eradication, and recovery; and post-incident activity—AWS ProServe Global Financial Services Senior Engagement Manager Harikumar Subramonion noted that, to fully benefit from the cloud, you need to embrace automation. Automation benefits the third phase of the incident response process by speeding up containment, and reducing mean time to response.

Citibank Head of Cloud Security Operations Elvis Velez and Vice President of Cloud Security Damien Burks described how Citi built the Cloud Containment Automation Framework (CCAF) from the ground up by using AWS Step Functions and AWS Lambda, enabling them to respond to events 24/7 without human error, and reduce the time it takes to contain resources from 4 hours to 15 minutes. Velez described how Citi uses adversary emulation exercises that use the MITRE ATT&CK Cloud Matrix to simulate realistic attacks on AWS environments, and continuously validate their ability to effectively contain incidents.

Innovate and do more with less

Security operations teams are often understaffed, making it difficult to keep up with alerts. According to data from CyberSeek, there are currently 69 workers available for every 100 cybersecurity job openings.

Effectively evaluating security and compliance posture is critical, despite resource constraints. In Centralizing security at scale with Security Hub and Intuit’s experience, AWS Senior Solutions Architect Craig Simon, AWS Senior Security Hub Product Manager Dora Karali, and Intuit Principal Software Engineer Matt Gravlin discussed how to ease security management with Security Hub. Fortune 500 financial software provider Intuit has approximately 2,000 AWS accounts, 10 million AWS resources, and receives 20 million findings a day from AWS services through Security Hub. Gravlin detailed Intuit’s Automated Compliance Platform (ACP), which combines Security Hub and AWS Config with an internal compliance solution to help Intuit reduce audit timelines, effectively manage remediation, and make compliance more consistent.

“By using Security Hub, we leveraged AWS expertise with their regulatory controls and best practice controls. It helped us keep up to date as new controls are released on a regular basis. We like Security Hub’s aggregation features that consolidate findings from other AWS services and third-party providers. I personally call it the super aggregator. A key component is the Security Hub to Amazon EventBridge integration. This allowed us to stream millions of findings on a daily basis to be inserted into our ACP database.” — Matt Gravlin, principal software engineer, Intuit

At AWS re:Inforce, we launched a new Security Hub capability for automating actions to update findings. You can now use rules to automatically update various fields in findings that match defined criteria. This allows you to automatically suppress findings, update the severity of findings according to organizational policies, change the workflow status of findings, and add notes. With automation rules, Security Hub provides you a simplified way to build automations directly from the Security Hub console and API. This reduces repetitive work for cloud security and DevOps engineers and can reduce mean time to response.

In Continuous innovation in AWS detection and response services, AWS Worldwide Security Specialist Senior Manager Himanshu Verma and GuardDuty Senior Manager Ryan Holland highlighted new features that can help you gain actionable insights that you can use to enhance your overall security posture. After mapping AWS security capabilities to the core functions of the NIST Cybersecurity Framework, Verma and Holland provided an overview of AWS threat detection and response services that included a technical demonstration.

Bolstering incident response with AWS Wickr enterprise integrations highlighted how incident responders can collaborate securely during a security event, even on a compromised network. AWS Senior Security Specialist Solutions Architect Wes Wood demonstrated an innovative approach to incident response communications by detailing how you can integrate the end-to-end encrypted collaboration service AWS Wickr Enterprise with GuardDuty and AWS WAF. Using Wickr Bots, you can build integrated workflows that incorporate GuardDuty and third-party findings into a more secure, out-of-band communication channel for dedicated teams.

Evolve your incident response maturity

AWS re:Inforce featured many more highlights on incident response, including How to run security incident response in your Amazon EKS environment and Investigating incidents with Amazon Security Lake and Jupyter notebooks code talks, as well as the announcement of our Cyber Insurance Partners program. Content presented throughout the conference made one thing clear: AWS is working harder than ever to help you gain the insights that you need to strengthen your organization’s security posture, and accelerate incident response in the cloud.

To watch AWS re:Inforce sessions on demand, see the AWS re:Inforce playlists on YouTube.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Anne Grahn

Anne Grahn

Anne is a Senior Worldwide Security GTM Specialist at AWS based in Chicago. She has more than a decade of experience in the security industry, and focuses on effectively communicating cybersecurity risk. She maintains a Certified Information Systems Security Professional (CISSP) certification.

Author

Himanshu Verma

Himanshu is a Worldwide Specialist for AWS Security Services. In this role, he leads the go-to-market creation and execution for AWS Security Services, field enablement, and strategic customer advisement. Prior to AWS, he held several leadership roles in Product Management, engineering and development, working on various identity, information security, and data protection technologies. He obsesses brainstorming disruptive ideas, venturing outdoors, photography, and trying various “hole in the wall” food and drinking establishments around the globe.

Jesus Federico

Jesus Federico

Jesus is a Principal Solutions Architect for AWS in the telecommunications vertical, working to provide guidance and technical assistance to communication service providers on their cloud journey. He supports CSPs in designing and implementing secure, resilient, scalable, and high-performance applications in the cloud.

How GoDaddy Implemented a Multi-Region Event-Driven Platform at Scale

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/aws/how-godaddy-implemented-a-multi-region-event-driven-platform-at-scale/

GoDaddy, a leading global provider of domain registration and web hosting services, has served over 84 million domains and 22 million customers since its establishment in 1997. Among its various internal systems, the Customer Signal Platform provides tooling to capture, analyze, and act on customer and product data to drive better business outcomes. With this platform, GoDaddy can track user visits and interactions on its website and use meaningful event data to improve its customer experience and overall business performance.

Nowadays, the Customer Signal Platform processes 400 million events every day. As GoDaddy expands its integrations, it aims to increase this number to 2 billion events per day in the near future.

When building the Customer Signal Platform, GoDaddy had three main requirements for the system architecture:

  1. Minimize their operational load.
  2. Scale automatically as traffic changes.
  3. Provide high availability and ensure that all the customer signals are captured.

Amazon EventBridge Event Bus
After evaluating many options against their requirements, GoDaddy decided to implement the customer signal platform using Amazon EventBridge Event Bus. EventBridge Event Bus is a serverless event bus that helps you receive, filter, transform, route, and deliver events. Because EventBridge is serverless, it requires minimal configuration to get started and scales automatically—GoDaddy’s first two requirements were checked.

To comply with the third requirement, the solution needed to provide business continuity and ensure that no event is lost from the moment the client produces it until it gets to the platform to be analyzed. EventBridge Event Bus comes with many features that helped GoDaddy build their application with this requirement in mind.

The main feature that GoDaddy took advantage of was global endpoints. EventBridge global endpoints provide a reliable and simple way to improve the business continuity of event-driven applications. This new feature, added in 2022, allows customers to build a multi-Region event-driven application.

EventBridge Global Endpoints
Global endpoints allow you to configure a managed DNS endpoint in EventBridge, to which your applications will send events. Then you need to configure two custom event buses in two distinct AWS Regions. One is the primary Region, and the other is the failover, or secondary Region. The failover of events is decided based on the health indicated by an Amazon Route 53 health check. When the health check is healthy, the events are routed from the global endpoint to the custom event bus in the primary Region. And if the health check is unhealthy, then the global endpoint will send the events to the event bus in the secondary Region.

Healthcheck status

The simplest configuration for global endpoints is the active/archive configuration. This configuration provides business continuity and simplicity at the same time. The active/archive configuration defines two different Regions. The primary Region is where the application is deployed and all the business processes are happening. The archive Region is where only a custom bus is deployed and all the events are archived.

In addition, there is a bidirectional replication rule between the buses in separate Regions. In the normal case, when there are no errors, whenever an event arrives at the custom bus in the primary Region, the event is automatically replicated to the archive custom bus in the secondary Region.

In the case of failover, the global endpoint redirects the events to the secondary Region, where they get archived for processing at another time.

Active/ Archive configuration

GoDaddy Implementation of Global Endpoints
GoDaddy was looking for a solution that minimized their operations load while still providing business continuity, and that is why they adopted global endpoints and the active/archive configuration. In this way, they could have the event processing logic in their primary Region and have a secondary Region in case of any issues.

In their configuration, events are archived in the secondary Region for 30 days, after which the events expire. In the case of a failover, because they don’t need to process the events in real time, they collect them in the archive. If the issue is resolved within 24 hours, the retention period for the replication rule, the events are sent automatically to the primary Region. If the issue is solved in more than 24 hours the events need to be replayed to the primary Region.

The following image shows what their current solution looks like. They are working with two Regions. US West (Oregon) is their primary Region and is the location of the data lake, which is the primary consumer of the events. US East (N. Virginia) is the secondary Region. Events are being produced in different clients; from the clients, they are sent to Amazon API Gateway. GoDaddy deployed two API Gateways in their two Regions. The events are sent to the API Gateway with the smallest latency from the client. To do that, they use latency-based routing provided by Amazon Route 53. Then events are sent to an AWS Lambda function that validates the events and forwards them to the EventBridge global endpoint at the DNS level.

GoDaddy architecture

The global endpoint is configured with the active/archive setup, and the failover is configured to be triggered via a Route 53 health check that monitors an Amazon CloudWatch alarm. That alarm observes the IngestionToInvocationStartLatency metric in the primary Region.

IngestionToInvocationStartLatency is a service-level metric that exposes the time to process events from the point at which they are ingested by EventBridge to the point the first invocation of a target in the configured rules is made. This metric is measured across all the rules in your bus and provides an indication of the health of the EventBridge service. Any extended periods of high latency over 30 seconds indicate a service disruption.

When the system is in the normal state, the events are forwarded from the global endpoint to the custom ingress event bus in the primary Region. That custom event bus has replication enabled; this means that all the events that arrive at the bus get replicated automatically in the secondary Region custom ingress event bus.

All the events received by the ingress event bus are sent to the enrichment function. This function performs basic validation and authentication, and it enriches the event data to make sure that all the events from different clients are standard.

From there, the events are forwarded to the data platform event bus to be sent to the different consumer targets. The main target is their data lake solution, which analyzes all the events.

What Was the Impact?
For GoDaddy, business continuity is important, and their customer signals are not getting lost due to any issue with their platform. This makes them confident that they can expand their customer signal platforms from 400 million events per day to 2 billion events per day without introducing any additional operations overhead.

Now, they can confidently process hundreds of millions of events per day to their system, and they can keep on growing. The following image shows the number of events ingested by global endpoints in a normal day.

Events ingested

While GoDaddy’s use of the active/archive pattern enables them to ensure they never lose any events, they’re already starting to see certain use cases where they want to minimize any delays in processing their events, even when service disruptions occur. Because they’re already replicating their events to a secondary Region, they can deploy their most critical consumers to both Regions and enable an active/active configuration for their mission-critical systems. Active/active configuration allows you to process parallel events in both the primary and secondary Regions, simplifying the processing of events even during disruptions and enabling business continuity.

The vision when building the Customer Signal Platform was to align with GoDaddy’s high bar for reliability, scalability, and maintainability and, at the same time, keep the platform self-service so that developers can focus on business needs. This led GoDaddy to choose Amazon EventBridge global endpoints and serverless technologies to build this solution.

GoDaddy Customer Signal Platform is an excellent example of what serverless technologies enable. By leveraging the cloud to handle as much of the undifferentiated heavy lifting as possible, GoDaddy has reduced the operational complexity of setting up an event bus for a multi-Region strategy, implemented failover mechanisms in the case of Regional distruptions, and ensured that events are not lost by enabling replication. Global endpoints active/archive configuration improves the availability of customer applications with the least amount of configuration changes.

If you want to get started with EventBridge global endpoints, you can check out this talk on event-driven applications. For a working demo on how to use EventBridge global endpoints for failover events, check out this Serverless Land repository.

Marcia

AWS Week in Review – AWS Documentation Updates, Amazon EventBridge is Faster, and More – May 22, 2023

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/aws-week-in-review-aws-documentation-updates-amazon-eventbridge-is-faster-and-more-may-22-2023/

AWS Data Hero Anahit Pogosova keynote at CloudConf 2023Here are your AWS updates from the previous 7 days. Last week I was in Turin, Italy for CloudConf, a conference I’ve had the pleasure to participate in for the last 10 years. AWS Hero Anahit Pogosova was also there sharing a few serverless tips in front of a full house. Here’s a picture I took from the last row during her keynote.

On Thursday, May 25, I’ll be at the AWS Community Day in Dublin to celebrate the 10 years of the local AWS User Group. Say hi if you’re there!

Last Week’s Launches
Last week was packed with announcements! Here are the launches that got my attention:

Amazon SageMakerGeospatial capabilities are now generally available with security updates and more use case samples.

Amazon DetectiveSimplify the investigation of AWS Security Findings coming from new sources such as AWS IAM Access Analyzer, Amazon Inspector, and Amazon Macie.

Amazon EventBridge – EventBridge now delivers events up to 80% faster than before, as measured by the time an event is ingested to the first invocation attempt. No change is required on your side.

AWS Control Tower – The service has launched 28 new proactive controls that allow you to block non-compliant resources before they are provisioned for services such as AWS OpenSearch Service, AWS Auto Scaling, Amazon SageMaker, Amazon API Gateway, and Amazon Relational Database Service (Amazon RDS). Check out the original posts from when proactive controls were launched.

Amazon CloudFront – CloudFront now supports two new control directives to help improve performance and availability: stale-while-revalidate (to immediately deliver stale responses to users while it revalidates caches in the background) and the stale-if-error cache (to define how long stale responses should be reused if there’s an error).

Amazon Timestream – Timestream now enables to export query results to Amazon S3 in a cost-effective and secure manner using the new UNLOAD statement.

AWS Distro for OpenTelemetryThe tail sampling and the group-by-trace processors are now generally available in the AWS Distro for OpenTelemetry (ADOT) collector. For example, with tail sampling, you can define sampling policies such as “ingest 100% of all error cases and 5% of all success cases.”

AWS DataSync – You can now use DataSync to copy data to and from Amazon S3 compatible storage on AWS Snowball Edge Compute Optimized devices.

AWS Device Farm – Device Farm now supports VPC integration for private devices, for example, when an unreleased version of an app is accessing a staging environment and tests are accessing internal packages only accessible via private networking. Read more at Access your private network from real mobile devices using AWS Device Farm.

Amazon Kendra – Amazon Kendra now helps you search across different content repositories with new connectors for Gmail, Adobe Experience Manager Cloud, Adobe Experience Manager On-Premise, Alfresco PaaS, and Alfresco Enterprise. There is also an updated Microsoft SharePoint connector.

Amazon Omics – Omics now offers pre-built bioinformatic workflows, synchronous upload capability, integration with Amazon EventBridge, and support for Graphical Processing Units (GPUs). For more information, check out New capabilities make it easier for healthcare and life science customers to get started, build applications, and scale-up on Amazon Omics.

Amazon Braket – Braket now supports Aria, IonQ’s largest and highest fidelity publicly available quantum computing device to date. To learn more, read Amazon Braket launches IonQ Aria whith built-in error mitigation.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
A few more news items and blog posts you might have missed:

AWS Documentation home page screenshot.AWS Documentation – The AWS Documentation home page has been redesigned. Leave your feedback there to let us know what you think or to suggest future improvements. Last week we also announced that we are retiring the AWS Documentation GitHub repo to focus our resources to directly improve the documentation and the website.

Peloton case studyPeloton embraces Amazon Redshift to unlock the power of data during changing times.

Zoom case studyLearn how Zoom implemented streaming log ingestion and efficient GDPR deletes using Apache Hudi on Amazon EMR.

Nice solutionIntroducing an image-to-speech Generative AI application using SageMaker and Hugging Face.

For AWS open-source news and updates, check out the latest newsletter curated by Ricardo to bring you the most recent updates on open-source projects, posts, events, and more.

Upcoming AWS Events
Here are some opportunities to meet and learn:

AWS Data Insights Day (May 24) – A virtual event to discover how to innovate faster and more cost-effectively with data. This event focuses on customer voices, deep-dive sessions, and best practices of Amazon Redshift. You can register here.

AWS Silicon Innovation Day (June 21) – AWS has designed and developed purpose-built silicon specifically for the cloud. Join to learn AWS innovations in custom-designed Amazon EC2 chips built for high performance and scale in the cloud. Register here.

AWS re:Inforce (June 13–14) – You can still register for AWS re:Inforce. This year it is taking place in Anaheim, California.

AWS Global Summits – Sign up for the AWS Summit closest to where you live: Hong Kong (May 23), India (May 25), Amsterdam (June 1), London (June 7), Washington, DC (June 7-8), Toronto (June 14), Madrid (June 15), and Milano (June 22). If you want to meet, I’ll be at the one in London.

AWS Community Days – Join these community-led conferences where event logistics and content is planned, sourced, and delivered by community leaders: Dublin, Ireland (May 25), Shenzhen, China (May 28), Warsaw, Poland (June 1), Chicago, USA (June 15), and Chile (July 1).

That’s all from me for this week. Come back next Monday for another Week in Review!

Danilo

This post is part of our Week in Review series. Check back each week for a quick roundup of interesting news and announcements from AWS!

Learn How to Modernize Your Applications at AWS Serverless Innovation Day

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/aws/learn-how-to-modernize-your-applications-at-aws-serverless-innovation-day/

Join us on Wednesday, May 17, for AWS Serverless Innovation Day, a free full-day virtual event. You will learn about AWS Serverless technologies and event-driven architectures from customers, experts, and leaders.

AWS Serverless Innovation Day is an event to empower builders and technical decision-makers with different AWS Serverless technologies, including AWS Lambda, Amazon Elastic Container Service (Amazon ECS) with AWS Fargate, Amazon EventBridge, and AWS Step Functions. The talks of the day will cover three key topics: event-driven architectures, serverless containers, and serverless functions, and how they can be utilized to build and modernize applications. Application modernization is a priority for organizations this year, and serverless helps to increase the software delivery speed and reduce the total cost of ownership.

AWS Serverless Innovation Day

Eric Johnson and Jessica Deen will be the hosts for the event. Holly Mesrobian, VP of Serverless Compute at AWS, will deliver the welcome keynote and share AWS’s vision for Serverless. The day ends with closing remarks from James Beswick and Usman Khalid, Events and Workflows Director at AWS.

The event is split into three groups of talks: event-driven architecture, serverless containers, and Lambda-based applications. Each group kicks off with a fireside chat between AWS customers and an AWS leader. You can learn how organizations, such as Capital One, PostNL, Pentasoft, Delta Air Lines, and Smartsheets, are using AWS Serverless technologies to solve their most challenging problems and continue to innovate.

During the day, all the sessions include demos and use cases, where you can learn the best practices and how to build applications. If you cannot attend all day, here are some of my favorite sessions to watch:

  • Building with serverless workflows at scaleBen Smith will show you how to unleash the power of AWS Step Functions.
  • Event design and event-first development – In this session, David Boyne will show you a robust approach to event design with Amazon EventBridge.
  • Best practices for AWS Lambda – You will learn from Julian Wood how to get the most out of your functions.
  • Optimizing for cost using Amazon ECSScott Coulton will show you how to reduce operational overhead from the control plane with Amazon ECS.

There is no up-front registration required to join the AWS Serverless Innovation Day, but if you want to be notified before the event starts, get in-depth news, articles, and event updates, and get a notification when the on-demand videos are available, you can register on the event page. The event will be streamed on Twitch, LinkedIn Live, YouTube, and Twitter.

See you there.

Marcia

Automating stopping and starting Amazon MWAA environments to reduce cost

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/automating-stopping-and-starting-amazon-mwaa-environments-to-reduce-cost/

This was written by Uma Ramadoss, Specialist Integration Services, and Chandan Rupakheti, Solutions Architect.

This blog post shows how you can save cost by automating the stopping and starting of an Amazon Managed Workflows for Apache Airflow (Amazon MWAA) environment. It describes how you can retain the data stored in a metadata database and presents an automated solution you can use in your AWS account.

Customers run end to end data pipelines at scale with MWAA. It is a common best practice to run non-production environments for development and testing. A nonproduction environment often does not need to run throughout the day due to factors such as working hours of the development team. As there is no automatic way to stop an MWAA environment when not in use and deleting an environment causes metadata loss, customers often run it continually and pay the full cost.

Overview

Amazon MWAA has a distributed architecture with multiple components such as scheduler, worker, webserver, queue, and database. Customers build data pipelines as Directed Acyclic Graphs (DAGs) and run in Amazon MWAA. The DAGs use variables and connections from the Amazon MWAA metadata database. The history of DAG runs and related data are stored in the same metadata database. The database also stores other information such as user roles and permissions.

When you delete the Amazon MWAA environment, all the components including the database are deleted so that you do not incur any cost. As this normal deletion results in loss of metadata, you need a customized solution to back up the data and to automate the deletion and recreation.

The sample application deletes and recreates your MWAA environment at a scheduled interval defined by you using Amazon EventBridge Scheduler. It exports all metadata into an Amazon S3 bucket before deletion and imports the metadata back to the environment after creation. As this is a managed database and you cannot access the database outside the Amazon MWAA environment, it uses DAGs to import and export the data. The entire process is orchestrated using AWS Step Functions.

Deployment architecture

The sample application is in a GitHub repository. Use the instructions in the readme to deploy the application.

Sample architecture

The sample application deploys the following resources –

  1. A Step Functions state machine to orchestrate the steps needed to delete the MWAA environment.
  2. A Step Functions state machine to orchestrate the steps needed to recreate the MWAA environment.
  3. EventBridge Scheduler rules to trigger the state machines at the scheduled time.
  4. An S3 bucket to store metadata database backup and environment details.
  5. Two DAG files uploaded to the source S3 bucket configured with the MWAA environment. The export DAG exports metadata from the MWAA metadata database to backup S3 bucket. The import DAG restores the metadata from the backup S3 bucket to the newly created MWAA environment.
  6. AWS Lambda functions for triggering the DAGs using MWAA CLI API.
  7. A Step Functions state machine to wait for the long-running MWAA creation and deletion process.
  8. Amazon EventBridge rule to notify on state machine failures.
  9. Amazon Simple Notification Service (Amazon SNS) topic as a target to the EventBridge rule for failure notifications.
  10. Amazon Interface VPC Endpoint for Step Functions for MWAA environment deployed in the private mode.

Stop workflow

At a scheduled time, Amazon EventBridge Scheduler triggers a Step Functions state machine to stop the MWAA environment. The state machine performs the following actions:

Stop workflow

  1. Fetch Amazon MWAA environment details such as airflow configurations, IAM execution role, logging configurations and VPC details.
  2. If the environment is not in the “AVAILABLE” status, it fails the workflow by branching to the “Pausing unsuccessful” state.
  3. Otherwise, it runs the normal workflow and stores the environment details in an S3 bucket so that Start workflow can recreate the environment with this data.
  4. Trigger an MWAA DAG using AWS Lambda function to export metadata to the Amazon S3 bucket. This step uses Step Functions to wait for callback token integration.
  5. Resume the workflow when the task token is returned from the MWAA DAG.
  6. Delete Amazon MWAA environment.
  7. Wait to confirm the deletion.

Start workflow

At a scheduled time, EventBridge Scheduler triggers the Step Functions state machine to recreate the MWAA environment. The steps in the state machine perform the following actions:

Start workflow

  1. Retrieve the environment details stored in Amazon S3 bucket by the stop workflow.
  2. Create an MWAA environment with the same configuration as the original.
  3. Trigger an MWAA DAG through the Lambda function to restore the metadata from the S3 bucket to the newly created environment.

Cost savings

Consider a small MWAA environment in us-east-2 with a minimum of one worker, a maximum of one worker, and 1GB data storage. At the time of this writing, the monthly cost of the environment is $357.80. Let’s assume you use this environment between 6 am and 6 pm on weekdays.

The schedule in the env file of the sample application looks like:

MWAA_PAUSE_CRON_SCHEDULE=’0 18 ? * MON-FRI *’
MWAA_RESUME_CRON_SCHEDULE=’30 5 ? * MON-FRI *’

As MWAA environment creation takes anywhere between 20 and 30 minutes, the MWAA_RESUME_CRON_SCHEDULE is set at 5.30 pm.

Assuming 21 weekdays per month, the monthly cost of the environment is $123.48 and is 65.46% less compared to running the environment continuously:

  • 21 weekdays * 12 hours * 0.49 USD per hour = $123.48

Additional considerations

The sample application only restores at-store data. Though the deletion process pauses all the DAGs before making the backup, it cannot stop any running tasks or in-flight messages in the queue. It also does not backup tasks that are not in completed state. This can result in task history loss for the tasks that were running during the backup.

Over time, the metadata grows in size, which can increase latency in query performance. You can use a DAG as shown in the example to clean up the database regularly.

Avoid setting the catchup by default configuration flag in the environment setting to true or in the DAG definition unless it is required. Catch up feature runs all the DAG runs that are missed for any data interval. When the environment is created again, if the flag is true, it catches up with the missed DAG runs and can overload the environment.

Conclusion

Automating the deletion and recreation of Amazon MWAA environments is a powerful solution for cost optimization and efficient management of resources. By following the steps outlined in this blog post, you can ensure that your MWAA environment is deleted and recreated without losing any of the metadata or configurations. This allows you to deploy new code changes and updates more quickly and easily, without having to configure your environment each time manually.

The potential cost savings of running your MWAA environment for only 12 hours on weekdays are significant. The example shows how you can save up to 65% of your monthly costs by choosing this option. This makes it an attractive solution for organizations that are looking to reduce cost while maintaining a high level of performance.

Visit the samples repository to learn more about Amazon MWAA. It contains a wide variety of examples and templates that you can use to build your own applications.

For more serverless learning resources, visit Serverless Land.

Let’s Architect! Designing serverless solutions

Post Syndicated from Luca Mezzalira original https://aws.amazon.com/blogs/architecture/lets-architect-designing-serverless-solutions/

During his re:Invent 2022 keynote, Werner Vogels, AWS Vice President and Chief Technology Officer, emphasized the asynchronous nature of our world and the challenges associated with incorporating asynchronicity into our architectures. AWS serverless services can help users concentrate on the asynchronous aspects of their workloads, easing the execution of event-driven architectures and enabling the adoption of effective integration patterns for communication both within and beyond a bounded context.

In this edition of Let’s Architect!, we offer an in-depth exploration of the architecture of serverless AWS services, such as AWS Lambda. We also present a new workshop centered on design patterns employing serverless AWS services, which ultimately delivers valuable insights on implementing event-driven architectures within systems.

A closer look at AWS Lambda

This video is the perfect companion for those seeking to learn and master a Lambda architecture, empowering you to effectively leverage its capabilities in your workloads.

With the knowledge gained from this video, you will be well-equipped to design your functions’ code in a highly optimized manner, ensuring efficient performance and resource utilization. Furthermore, a comprehensive understanding of Lambda functions can help identify and apply the most suitable approach to cloud workloads, resulting in an agile and robust cloud infrastructure that meets a project’s unique requirements.

Take me to this video!

Discover how AWS Lambda functions work under the hood

Discover how AWS Lambda functions work under the hood

Implementing an event-driven serverless story generation application with ChatGPT and DALL-E

This example of an event-driven serverless architecture showcases the power of leveraging AWS services and AI technologies to develop innovative solutions. Built upon a foundation of serverless services, including Amazon EventBridge, Amazon DynamoDB, Lambda, Amazon Simple Storage Service, and managed artificial intelligence (AI ) services like Amazon Polly, this architecture demonstrates the seamless capacity to create daily stories with a scheduled launch. By utilizing EventBridge scheduler, an Lambda function is initiated every night to generate new content. The integration of AI services, like ChatGPT and DALL-E, further elevates the solution, as their compatibility with the serverless model enables efficient and dynamic content creation. This case serves as a testament to the potential of combining event-driven serverless architectures, with cutting-edge AI technologies for inventive and impactful applications.

Take me to this Compute Blog post!

How to build an event-driven architecture with serverless AWS services integrating ChatGPT and DALL-E

How to build an event-driven architecture with serverless AWS services integrating ChatGPT and DALL-E

AWS Workshop Studio: Serverless Patterns

The AWS Serverless Patterns workshop offers a comprehensive learning experience to enhance your understanding of architectural patterns applicable to serverless projects. Throughout the workshop, participants will delve into various patterns, such as synchronous and asynchronous implementations, tailored to meet the demands of modern serverless applications. This hands-on approach ensures a production-ready understanding, encompassing crucial topics like testing serverless workloads, establishing automation pipelines, and more. Take this workshop to elevate your serverless architecture knowledge!

Take me to the serverless workshop!

The high-level architecture of the workshops modules

The high-level architecture of the workshops modules

Building Serverlesspresso: Creating event-driven architectures

Serverlesspresso is an event-driven, serverless workload that uses EventBridge and AWS Step Functions to coordinate events across microservices and support thousands of orders per day. This comprehensive session delves into design considerations, development processes, and valuable lessons learned from creating a production-ready solution. Discover practical patterns and extensibility options that contribute to a robust, scalable, and cost-effective application. Gain insights into combining EventBridge and Step Functions to address complex architectural challenges in larger applications.

Take me to this video!

How to leverage AWS Step Functions for orchestrating your workflows

How to leverage AWS Step Functions for orchestrating your workflows

See you next time!

Thanks for joining our conversation on serverless solutions! We’ll see you next time when we talk about AWS microservices.

Can’t get enough of the Let’s Architect! series? Visit the Let’s Architect! page of the AWS Architecture Blog!

Extending a serverless, event-driven architecture to existing container workloads

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/extending-a-serverless-event-driven-architecture-to-existing-container-workloads/

This post is written by Dhiraj Mahapatro, Principal Specialist SA, and Sascha Moellering, Principal Specialist SA, and Emily Shea, WW Lead, Integration Services.

Many serverless services are a natural fit for event-driven architectures (EDA), as events invoke them and only run when there is an event to process. When building in the cloud, many services emit events by default and have built-in features for managing events. This combination allows customers to build event-driven architectures easier and faster than ever before.

The insurance claims processing sample application in this blog series uses event-driven architecture principles and serverless services like AWS LambdaAWS Step FunctionsAmazon API GatewayAmazon EventBridge, and Amazon SQS.

When building an event-driven architecture, it’s likely that you have existing services to integrate with the new architecture, ideally without needing to make significant refactoring changes to those services. As services communicate via events, extending applications to new and existing microservices is a key benefit of building with EDA. You can write those microservices in different programming languages or running on different compute options.

This blog post walks through a scenario of integrating an existing, containerized service (a settlement service) to the serverless, event-driven insurance claims processing application described in this blog post.

Overview of sample event-driven architecture

The sample application uses a front-end to sign up a new user and allow the user to upload images of their car and driver’s license. Once signed up, they can file a claim and upload images of their damaged car. Previously, it did not yet integrate with a settlement service for completing the claims and settlement process.

In this scenario, the settlement service is a brownfield application that runs Spring Boot 3 on Amazon ECS with AWS Fargate. AWS Fargate is a serverless, pay-as-you-go compute engine that lets you focus on building container applications without managing servers.

The Spring Boot application exposes a REST endpoint, which accepts a POST request. It applies settlement business logic and creates a settlement record in the database for a car insurance claim. Your goal is to make settlement work with the new EDA application that is designed for claims processing without re-architecting or rewriting. Customer, claims, fraud, document, and notification are the other domains that are shown as blue-colored boxes in the following diagram:

Reference architecture

Project structure

The application uses AWS Cloud Development Kit (CDK) to build the stack. With CDK, you get the flexibility to create modular and reusable constructs imperatively using your language of choice. The sample application uses TypeScript for CDK.

The following project structure enables you to build different bounded contexts. Event-driven architecture relies on the choreography of events between domains. The object oriented programming (OOP) concept of CDK helps provision the infrastructure to separate the domain concerns while loosely coupling them via events.

You break the higher level CDK constructs down to these corresponding domains:

Comparing domains

Application and infrastructure code are present in each domain. This project structure creates a seamless way to add new domains like settlement with its application and infrastructure code without affecting other areas of the business.

With the preceding structure, you can use the settlement-service.ts CDK construct inside claims-processing-stack.ts:

const settlementService = new SettlementService(this, "SettlementService", {
  bus,
});

The only information the SettlementService construct needs to work is the EventBridge custom event bus resource that is created in the claims-processing-stack.ts.

To run the sample application, follow the setup steps in the sample application’s README file.

Existing container workload

The settlement domain provides a REST service to the rest of the organization. A Docker containerized Spring Boot application runs on Amazon ECS with AWS Fargate. The following sequence diagram shows the synchronous request-response flow from an external REST client to the service:

Settlement service

  1. External REST client makes POST /settlement call via an HTTP API present in front of an internal Application Load Balancer (ALB).
  2. SettlementController.java delegates to SettlementService.java.
  3. SettlementService applies business logic and calls SettlementRepository for data persistence.
  4. SettlementRepository persists the item in the Settlement DynamoDB table.

A request to the HTTP API endpoint looks like:

curl --location <settlement-api-endpoint-from-cloudformation-output> \
--header 'Content-Type: application/json' \
--data '{
  "customerId": "06987bc1-1234-1234-1234-2637edab1e57",
  "claimId": "60ccfe05-1234-1234-1234-a4c1ee6fcc29",
  "color": "green",
  "damage": "bumper_dent"
}'

The response from the API call is:

API response

You can learn more here about optimizing Spring Boot applications on AWS Fargate.

Extending container workload for events

To integrate the settlement service, you must update the service to receive and emit events asynchronously. The core logic of the settlement service remains the same. When you file a claim, upload damaged car images, and the application detects no document fraud, the settlement domain subscribes to Fraud.Not.Detected event and applies its business logic. The settlement service emits an event back upon applying the business logic.

The following sequence diagram shows a new interface in settlement to work with EDA. The settlement service subscribes to events that a producer emits. Here, the event producer is the fraud service that puts an event in an EventBridge custom event bus.

Sequence diagram

  1. Producer emits Fraud.Not.Detected event to EventBridge custom event bus.
  2. EventBridge evaluates the rules provided by the settlement domain and sends the event payload to the target SQS queue.
  3. SubscriberService.java polls for new messages in the SQS queue.
  4. On message, it transforms the message body to an input object that is accepted by SettlementService.
  5. It then delegates the call to SettlementService, similar to how SettlementController works in the REST implementation.
  6. SettlementService applies business logic. The flow is like the REST use case from 7 to 10.
  7. On receiving the response from the SettlementService, the SubscriberService transforms the response to publish an event back to the event bus with the event type as Settlement.Finalized.

The rest of the architecture consumes this Settlement.Finalized event.

Using EventBridge schema registry and discovery

Schema enforces a contract between a producer and a consumer. A consumer expects the exact structure of the event payload every time an event arrives. EventBridge provides schema registry and discovery to maintain this contract. The consumer (the settlement service) can download the code bindings and use them in the source code.

Enable schema discovery in EventBridge before downloading the code bindings and using them in your repository. The code bindings provide a marshaller that unmarshals the incoming event from SQS queue to a plain old Java object (POJO) FraudNotDetected.java. You download the code bindings using the choice of your IDE. AWS Toolkit for IntelliJ makes it convenient to download and use them.

Download code bindings

The final architecture for the settlement service with REST and event-driven architecture looks like:

Final architecture

Transition to become fully event-driven

With the new capability to handle events, the Spring Boot application now supports both the REST endpoint and the event-driven architecture by running the same business logic through different interfaces. In this example scenario, as the event-driven architecture matures and the rest of the organization adopts it, the need for the POST endpoint to save a settlement may diminish. In the future, you can deprecate the endpoint and fully rely on polling messages from the SQS queue.

You start with using an ALB and Fargate service CDK ECS pattern:

const loadBalancedFargateService = new ecs_patterns.ApplicationLoadBalancedFargateService(
  this,
  "settlement-service",
  {
    cluster: cluster,
    taskImageOptions: {
      image: ecs.ContainerImage.fromDockerImageAsset(asset),
      environment: {
        "DYNAMODB_TABLE_NAME": this.table.tableName
      },
      containerPort: 8080,
      logDriver: new ecs.AwsLogDriver({
        streamPrefix: "settlement-service",
        mode: ecs.AwsLogDriverMode.NON_BLOCKING,
        logRetention: RetentionDays.FIVE_DAYS,
      })
    },
    memoryLimitMiB: 2048,
    cpu: 1024,
    publicLoadBalancer: true,
    desiredCount: 2,
    listenerPort: 8080
  });

To adapt to EDA, you update the resources to retrofit the SQS queue to receive messages and EventBridge to put events. Add new environment variables to the ApplicationLoadBalancerFargateService resource:

environment: {
  "SQS_ENDPOINT_URL": queue.queueUrl,
  "EVENTBUS_NAME": props.bus.eventBusName,
  "DYNAMODB_TABLE_NAME": this.table.tableName
}

Grant the Fargate task permission to put events in the custom event bus and consume messages from the SQS queue:

props.bus.grantPutEventsTo(loadBalancedFargateService.taskDefinition.taskRole);
queue.grantConsumeMessages(loadBalancedFargateService.taskDefinition.taskRole);

When you transition the settlement service to become fully event-driven, you do not need the HTTP API endpoint and ALB anymore, as SQS is the source of events.

A better alternative is to use QueueProcessingFargateService ECS pattern for the Fargate service. The pattern provides auto scaling based on the number of visible messages in the SQS queue, besides CPU utilization. In the following example, you can also add two capacity provider strategies while setting up the Fargate service: FARGATE_SPOT and FARGATE. This means, for every one task that is run using FARGATE, there are two tasks that use FARGATE_SPOT. This can help optimize cost.

const queueProcessingFargateService = new ecs_patterns.QueueProcessingFargateService(this, 'Service', {
  cluster,
  memoryLimitMiB: 1024,
  cpu: 512,
  queue: queue,
  image: ecs.ContainerImage.fromDockerImageAsset(asset),
  desiredTaskCount: 2,
  minScalingCapacity: 1,
  maxScalingCapacity: 5,
  maxHealthyPercent: 200,
  minHealthyPercent: 66,
  environment: {
    "SQS_ENDPOINT_URL": queueUrl,
    "EVENTBUS_NAME": props?.bus.eventBusName,
    "DYNAMODB_TABLE_NAME": tableName
  },
  capacityProviderStrategies: [
    {
      capacityProvider: 'FARGATE_SPOT',
      weight: 2,
    },
    {
      capacityProvider: 'FARGATE',
      weight: 1,
    },
  ],
});

This pattern abstracts the automatic scaling behavior of the Fargate service based on the queue depth.

Running the application

To test the application, follow How to use the Application after the initial setup. Once complete, you see that the browser receives a Settlement.Finalized event:

{
  "version": "0",
  "id": "e2a9c866-cb5b-728c-ce18-3b17477fa5ff",
  "detail-type": "Settlement.Finalized",
  "source": "settlement.service",
  "account": "123456789",
  "time": "2023-04-09T23:20:44Z",
  "region": "us-east-2",
  "resources": [],
  "detail": {
    "settlementId": "377d788b-9922-402a-a56c-c8460e34e36d",
    "customerId": "67cac76c-40b1-4d63-a8b5-ad20f6e2e6b9",
    "claimId": "b1192ba0-de7e-450f-ac13-991613c48041",
    "settlementMessage": "Based on our analysis on the damage of your car per claim id b1192ba0-de7e-450f-ac13-991613c48041, your out-of-pocket expense will be $100.00."
  }
}

Cleaning up

The stack creates a custom VPC and other related resources. Be sure to clean up resources after usage to avoid the ongoing cost of running these services. To clean up the infrastructure, follow the clean-up steps shown in the sample application.

Conclusion

The blog explains a way to integrate existing container workload running on AWS Fargate with a new event-driven architecture. You use EventBridge to decouple different services from each other that are built using different compute technologies, languages, and frameworks. Using AWS CDK, you gain the modularity of building services decoupled from each other.

This blog shows an evolutionary architecture that allows you to modernize existing container workloads with minimal changes that still give you the additional benefits of building with serverless and EDA on AWS.

The major difference between the event-driven approach and the REST approach is that you unblock the producer once it emits an event. The event producer from the settlement domain that subscribes to that event is loosely coupled. The business functionality remains intact, and no significant refactoring or re-architecting effort is required. With these agility gains, you may get to the market faster

The sample application shows the implementation details and steps to set up, run, and clean up the application. The app uses ECS Fargate for a domain service, but you do not limit it to just Fargate. You can also bring container-based applications running on Amazon EKS similarly to event-driven architecture.

Learn more about event-driven architecture on Serverless Land.

How CyberCRX cut ML processing time from 8 days to 56 minutes with AWS Step Functions Distributed Map

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/aws/how-cybercrx-cut-ml-processing-time-from-8-days-to-56-minutes-with-aws-step-functions-distributed-map/

Last December, Sébastien Stormacq wrote about the availability of a distributed map state for AWS Step Functions, a new feature that allows you to orchestrate large-scale parallel workloads in the cloud. That’s when Charles Burton, a data systems engineer for a company called CyberGRX, found out about it and refactored his workflow, reducing the processing time for his machine learning (ML) processing job from 8 days to 56 minutes. Before, running the job required an engineer to constantly monitor it; now, it runs in less than an hour with no support needed. In addition, the new implementation with AWS Step Functions Distributed Map costs less than what it did originally.

What CyberGRX achieved with this solution is a perfect example of what serverless technologies embrace: letting the cloud do as much of the undifferentiated heavy lifting as possible so the engineers and data scientists have more time to focus on what’s important for the business. In this case, that means continuing to improve the model and the processes for one of the key offerings from CyberGRX, a cyber risk assessment of third parties using ML insights from its large and growing database.

What’s the business challenge?
CyberGRX shares third-party cyber risk (TPCRM) data with their customers. They predict, with high confidence, how a third-party company will respond to a risk assessment questionnaire. To do this, they have to run their predictive model on every company in their platform; they currently have predictive data on more than 225,000 companies. Whenever there’s a new company or the data changes for a company, they regenerate their predictive model by processing their entire dataset. Over time, CyberGRX data scientists improve the model or add new features to it, which also requires the model to be regenerated.

The challenge is running this job for 225,000 companies in a timely manner, with as few hands-on resources as possible. The job runs a set of operations for each company, and every company calculation is independent of other companies. This means that in the ideal case, every company can be processed at the same time. However, implementing such a massive parallelization is a challenging problem to solve.

First iteration
With that in mind, the company built their first iteration of the pipeline using Kubernetes and Argo Workflows, an open-source container-native workflow engine for orchestrating parallel jobs on Kubernetes. These were tools they were familiar with, as they were already using them in their infrastructure.

But as soon as they tried to run the job for all the companies on the platform, they ran up against the limits of what their system could handle efficiently. Because the solution depended on a centralized controller, Argo Workflows, it was not robust, and the controller was scaled to its maximum capacity during this time. At that time, they only had 150,000 companies. And running the job with all of the companies took around 8 days, during which the system would crash and need to be restarted. It was very labor intensive, and it always required an engineer on call to monitor and troubleshoot the job.

The tipping point came when Charles joined the Analytics team at the beginning of 2022. One of his first tasks was to do a full model run on approximately 170,000 companies at that time. The model run lasted the whole week and ended at 2:00 AM on a Sunday. That’s when he decided their system needed to evolve.

Second iteration
With the pain of the last time he ran the model fresh in his mind, Charles thought through how he could rewrite the workflow. His first thought was to use AWS Lambda and SQS, but he realized that he needed an orchestrator in that solution. That’s why he chose Step Functions, a serverless service that helps you automate processes, orchestrate microservices, and create data and ML pipelines; plus, it scales as needed.

Charles got the new version of the workflow with Step Functions working in about 2 weeks. The first step he took was adapting his existing Docker image to run in Lambda using Lambda’s container image packaging format. Because the container already worked for his data processing tasks, this update was simple. He scheduled Lambda provisioned concurrency to make sure that all functions he needed were ready when he started the job. He also configured reserved concurrency to make sure that Lambda would be able to handle this maximum number of concurrent executions at a time. In order to support so many functions executing at the same time, he raised the concurrent execution quota for Lambda per account.

And to make sure that the steps were run in parallel, he used Step Functions and the map state. The map state allowed Charles to run a set of workflow steps for each item in a dataset. The iterations run in parallel. Because Step Functions map state offers 40 concurrent executions and CyberGRX needed more parallelization, they created a solution that launched multiple state machines in parallel; in this way, they were able to iterate fast across all the companies. Creating this complex solution, required a preprocessor that handled the heuristics of the concurrency of the system and split the input data across multiple state machines.

This second iteration was already better than the first one, as now it was able to finish the execution with no problems, and it could iterate over 200,000 companies in 90 minutes. However, the preprocessor was a very complex part of the system, and it was hitting the limits of the Lambda and Step Functions APIs due to the amount of parallelization.

Second iteration with AWS Step Functions

Third and final iteration
Then, during AWS re:Invent 2022, AWS announced a distributed map for Step Functions, a new type of map state that allows you to write Step Functions to coordinate large-scale parallel workloads. Using this new feature, you can easily iterate over millions of objects stored in Amazon Simple Storage Service (Amazon S3), and then the distributed map can launch up to 10,000 parallel sub-workflows to process the data.

When Charles read in the News Blog article about the 10,000 parallel workflow executions, he immediately thought about trying this new state. In a couple of weeks, Charles built the new iteration of the workflow.

Because the distributed map state split the input into different processors and handled the concurrency of the different executions, Charles was able to drop the complex preprocessor code.

The new process was the simplest that it’s ever been; now whenever they want to run the job, they just upload a file to Amazon S3 with the input data. This action triggers an Amazon EventBridge rule that targets the state machine with the distributed map. The state machine then executes with that file as an input and publishes the results to an Amazon Simple Notification Service (Amazon SNS) topic.

Final iteration with AWS Step Functions

What was the impact?
A few weeks after completing the third iteration, they had to run the job on all 227,000 companies in their platform. When the job finished, Charles’ team was blown away; the whole process took only 56 minutes to complete. They estimated that during those 56 minutes, the job ran more than 57 billion calculations.

Processing of the Distributed Map State

The following image shows an Amazon CloudWatch graph of the concurrent executions for one Lambda function during the time that the workflow was running. There are almost 10,000 functions running in parallel during this time.

Lambda concurrency CloudWatch graph

Simplifying and shortening the time to run the job opens a lot of possibilities for CyberGRX and the data science team. The benefits started right away the moment one of the data scientists wanted to run the job to test some improvements they had made for the model. They were able to run it independently without requiring an engineer to help them.

And, because the predictive model itself is one of the key offerings from CyberGRX, the company now has a more competitive product since the predictive analysis can be refined on a daily basis.

Learn more about using AWS Step Functions:

You can also check the Serverless Workflows Collection that we have available in Serverless Land for you to test and learn more about this new capability.

Marcia

Cross-account integration between SaaS platforms using Amazon AppFlow

Post Syndicated from Ramakant Joshi original https://aws.amazon.com/blogs/big-data/cross-account-integration-between-saas-platforms-using-amazon-appflow/

Implementing an effective data sharing strategy that satisfies compliance and regulatory requirements is complex. Customers often need to share data between disparate software as a service (SaaS) platforms within their organization or across organizations. On many occasions, they need to apply business logic to the data received from the source SaaS platform before pushing it to the target SaaS platform.

Let’s take an example. AnyCompany’s marketing team hosted an event at the Anaheim Convention Center, CA. The marketing team created leads based on the event in Adobe Marketo. An automated process downloaded the leads from Marketo in the marketing AWS account. These leads are then pushed to the sales AWS account. A business process picks up those leads, filters them based on a “Do Not Call” criteria, and creates entries in the Salesforce system. Now, the sales team can pursue those leads and continue to track the opportunities in Salesforce.

In this post, we show how to share your data across SaaS platforms in a cross-account structure using fully managed, low-code AWS services such as Amazon AppFlow, Amazon EventBridge, AWS Step Functions, and AWS Glue.

Solution overview

Considering our example of AnyCompany, let’s look at the data flow. AnyCompany’s Marketo instance is integrated with the producer AWS account. As the leads from Marketo land in the producer AWS account, they’re pushed to the consumer AWS account, which is integrated to Salesforce. Business logic is applied to the leads data in the consumer AWS account, and then the curated data is loaded into Salesforce.

We have used a serverless architecture to implement this use case. The following AWS services are used for data ingestion, processing, and load:

  • Amazon AppFlow is a fully managed integration service that enables you to securely transfer data between SaaS applications like Salesforce, SAP, Marketo, Slack, and ServiceNow, and AWS services like Amazon S3 and Amazon Redshift, in just a few clicks. With AppFlow, you can run data flows at nearly any scale at the frequency you choose—on a schedule, in response to a business event, or on demand. You can configure data transformation capabilities like filtering and validation to generate rich, ready-to-use data as part of the flow itself, without additional steps. Amazon AppFlow is used to download leads data from Marketo and upload the curated leads data into Salesforce.
  • Amazon EventBridge is a serverless event bus that lets you receive, filter, transform, route, and deliver events. EventBridge is used to track the events like receiving the leads data in the producer or consumer AWS accounts and then triggering a workflow.
  • AWS Step Functions is a visual workflow service that helps developers use AWS services to build distributed applications, automate processes, orchestrate microservices, and create data and machine learning (ML) pipelines. Step Functions is used to orchestrate the data processing.
  • AWS Glue is a serverless data preparation service that makes it easy to run extract, transform, and load (ETL) jobs. An AWS Glue job encapsulates a script that reads, processes, and then writes data to a new schema. This solution uses Python 3.6 AWS Glue jobs for data filtration and processing.
  • Amazon Simple Storage Service (Amazon S3) is an object storage service offering industry-leading scalability, data availability, security, and performance. Amazon S3 is used to store the leads data.

Let’s review the architecture in detail. The following diagram shows a visual representation of how this integration works.

The following steps outline the process for transferring and processing leads data using Amazon AppFlow, Amazon S3, EventBridge, Step Functions, AWS Glue, and Salesforce:

  1. Amazon AppFlow runs on a daily schedule and retrieves any new leads created within the last 24 hours (incremental changes) from Marketo.
  2. The leads are saved as Parquet format files in an S3 bucket in the producer account.
  3. When the daily flow is complete, Amazon AppFlow emits events to EventBridge.
  4. EventBridge triggers Step Functions.
  5. Step Functions copies the Parquet format files containing the leads from the producer account’s S3 bucket to the consumer account’s S3 bucket.
  6. Upon a successful file transfer, Step Functions publishes an event in the consumer account’s EventBridge.
  7. An EventBridge rule intercepts this event and triggers Step Functions in the consumer account.
  8. Step Functions calls an AWS Glue crawler, which scans the leads Parquet files and creates a table in the AWS Glue Data Catalog.
  9. The AWS Glue job is called, which selects records with the Do Not Call field set to false from the leads files, and creates a new set of curated Parquet files. We have used an AWS Glue job for the ETL pipeline to showcase how you can use purpose-built analytics service for complex ETL needs. However, for simple filtering requirements like Do Not Call, you can use the existing filtering feature of Amazon AppFlow.
  10. Step Functions then calls Amazon AppFlow.
  11. Finally, Amazon AppFlow populates the Salesforce leads based on the data in the curated Parquet files.

We have provided artifacts in this post to deploy the AWS services in your account and try out the solution.

Prerequisites

To follow the deployment walkthrough, you need two AWS accounts, one for the producer and other for the consumer. Use us-east-1 or us-west-2 as your AWS Region.

Consumer account setup:

Stage the data

To prepare the data, complete the following steps:

  1. Download the zipped archive file to use for this solution and unzip the files locally.

The AWS Glue job uses the glue-job.py script to perform ETL and populates the curated table in the Data Catalog.

  1. Create an S3 bucket called consumer-configbucket-<ACCOUNT_ID> via the Amazon S3 console in the consumer account, where ACCOUNT_ID is your AWS account ID.
  2. Upload the script to this location.

Create a connection to Salesforce

Follow the connection setup steps outlined in here. Please make a note of the Salesforce connector name.

Create a connection to Salesforce in the consumer account

Follow the connection setup steps outlined in Create Opportunity Object Flow.

Set up resources with AWS CloudFormation

We provided two AWS CloudFormation templates to create resources: one for the producer account, and one for the consumer account.

Amazon S3 now applies server-side encryption with Amazon S3 managed keys (SSE-S3) as the base level of encryption for every bucket in Amazon S3. Starting January 5, 2023, all new object uploads to Amazon S3 are automatically encrypted at no additional cost and with no impact on performance. We use this default encryption for both producer and consumer S3 buckets. If you choose to bring your own keys with AWS Key Management Service (AWS KMS), we recommend referring to Replicating objects created with server-side encryption (SSE-C, SSE-S3, SSE-KMS) for cross-account replication.

Launch the CloudFormation stack in the consumer account

Let’s start with creating resources in the consumer account. There are a few dependencies on the consumer account resources from the producer account. To launch the CloudFormation stack in the consumer account, complete the following steps:

  1. Sign in to the consumer account’s AWS CloudFormation console in the target Region.
  2. Choose Launch Stack.
    BDB-2063-launch-cloudformation-stack
  3. Choose Next.
  4. For Stack name, enter a stack name, such as stack-appflow-consumer.
  5. Enter the parameters for the connector name, object, and producer (source) account ID.
  6. Choose Next.
  7. On the next page, choose Next.
  8. Review the details on the final page and select I acknowledge that AWS CloudFormation might create IAM resources.
  9. Choose Create stack.

Stack creation takes approximately 5 minutes to complete. It will create the following resources. You can find them on the Outputs tab of the CloudFormation stack.

  • ConsumerS3Bucketconsumer-databucket-<consumer account id>
  • Consumer S3 Target Foldermarketo-leads-source
  • ConsumerEventBusArnarn:aws:events:<region>:<consumer account id>:event-bus/consumer-custom-event-bus
  • ConsumerEventRuleArnarn:aws:events:<region>:<consumer account id>:rule/consumer-custom-event-bus/consumer-custom-event-bus-rule
  • ConsumerStepFunctionarn:aws:states:<region>:<consumer account id>:stateMachine:consumer-state-machine
  • ConsumerGlueCrawlerconsumer-glue-crawler
  • ConsumerGlueJobconsumer-glue-job
  • ConsumerGlueDatabaseconsumer-glue-database
  • ConsumerAppFlowarn:aws:appflow:<region>:<consumer account id>:flow/consumer-appflow

Producer account setup:

Create a connection to Marketo

Follow the connection setup steps outlined in here. Please make a note of the Marketo connector name.

Launch the CloudFormation stack in the producer account

Now let’s create resources in the producer account. Complete the following steps:

  1. Sign in to the producer account’s AWS CloudFormation console in the source Region.
  2. Choose Launch Stack.
    BDB-2063-launch-cloudformation-stack
  3. Choose Next.
  4. For Stack name, enter a stack name, such as stack-appflow-producer.
  5. Enter the following parameters and leave the rest as default:
    • AppFlowMarketoConnectorName: name of the Marketo connector, created above
    • ConsumerAccountBucket: consumer-databucket-<consumer account id>
    • ConsumerAccountBucketTargetFolder: marketo-leads-source
    • ConsumerAccountEventBusArn: arn:aws:events:<region>:<consumer account id>:event-bus/consumer-custom-event-bus
    • DefaultEventBusArn: arn:aws:events:<region>:<producer account id>:event-bus/default


  6. Choose Next.
  7. On the next page, choose Next.
  8. Review the details on the final page and select I acknowledge that AWS CloudFormation might create IAM resources.
  9. Choose Create stack.

Stack creation takes approximately 5 minutes to complete. It will create the following resources. You can find them on the Outputs tab of the CloudFormation stack.

  • Producer AppFlowproducer-flow
  • Producer Bucketarn:aws:s3:::producer-bucket.<region>.<producer account id>
  • Producer Flow Completion Rulearn:aws:events:<region>:<producer account id>:rule/producer-appflow-completion-event
  • Producer Step Functionarn:aws:states:<region>:<producer account id>:stateMachine:ProducerStateMachine-xxxx
  • Producer Step Function Rolearn:aws:iam::<producer account id>:role/service-role/producer-stepfunction-role
  1. After successful creation of the resources, go to the consumer account S3 bucket, consumer-databucket-<consumer account id>, and update the bucket policy as follows:
{
    "Version": "2008-10-17",
    "Statement": [
        {
            "Sid": "AllowAppFlowDestinationActions",
            "Effect": "Allow",
            "Principal": {"Service": "appflow.amazonaws.com"},
            "Action": [
                "s3:PutObject",
                "s3:GetObject",
                "s3:ListBucket"
            ],
            "Resource": [
                "arn:aws:s3:::consumer-databucket-<consumer-account-id>",
                "arn:aws:s3:::consumer-databucket-<consumer-account-id>/*"
            ]
        }, {
            "Sid": "Producer-stepfunction-role",
            "Effect": "Allow",
            "Principal": {
                "AWS": "arn:aws:iam::<producer-account-id>:role/service-role/producer-stepfunction-role"
            },
            "Action": [
                "s3:ListBucket",
                "s3:GetObject",
                "s3:PutObject",
                "s3:PutObjectAcl"
            ],
            "Resource": [
                "arn:aws:s3:::consumer-databucket-<consumer-account-id>",
                "arn:aws:s3:::consumer-databucket-<consumer-account-id>/*"
            ]
        }
    ]
}

Validate the workflow

Let’s walk through the flow:

  1. Review the Marketo and Salesforce connection setup in the producer and consumer account respectively.

In the architecture section, we suggested scheduling the AppFlow (producer-flow) in the producer account. However, for quick testing purposes, we demonstrate how to manually run the flow on demand.

  1. Go to the AppFlow (producer-flow) in the producer account. On the Filters tab of the flow, choose Edit filters.
  2. Choose the Created At date range for which you have data.
  3. Save the range and choose Run flow.
  4. Review the producer S3 bucket.

AppFlow generates the files in the producer-flow prefix within this bucket. The files are temporarily located in the producer S3 bucket under s3://<producer-bucket>.<region>.<account-id>/producer-flow.

  1. Review the EventBridge rule and Step Functions state machine in the producer account.

The Amazon AppFlow job completion triggers an EventBridge rule (arn:aws:events:<region>:<producer account id>:rule/producer-appflow-completion-event, as noted in the Outputs tab of the CloudFromation stack in the Producer Account), which triggers the Step Functions state machine (arn:aws:states:<region>:<producer account id>:stateMachine:ProducerStateMachine-xxxx) in the producer account. The state machine copies the files to the consumer S3 bucket from the producer-flow prefix in the producer S3 bucket. Once file copy is complete, the state machine moves the files from the producer-flow prefix to the archive prefix in the producer S3 bucket. You can find the files in s3://<producer-bucket>.<region>.<account-id>/archive.

  1. Review the consumer S3 bucket.

The Step Functions state machine in the producer account copies the files to the consumer S3 bucket and sends an event to EventBridge in the consumer account. The files are located in the consumer S3 bucket under s3://consumer-databucket-<account-id>/marketo-leads-source/.

  1. Review the EventBridge rule (arn:aws:events:<region>:<consumer account id>:rule/consumer-custom-event-bus/consumer-custom-event-bus-rule) in the consumer account, which should have triggered the Step Function workflow (arn:aws:states:<region>:<consumer account id>:stateMachine:consumer-state-machine).

The AWS Glue crawler (consumer-glue-crawler) runs to update the metadata followed by the AWS Glue job (consumer-glue-job), which curates the data by applying the Do not call filter. The curated files are placed in s3://consumer-databucket-<account-id>/marketo-leads-curated/. After data curation, the flow is started as part of the state machine.

  1. Review the Amazon AppFlow job (arn:aws:appflow:<region>:<consumer account id>:flow/consumer-appflow) run status in the consumer account.

Upon a successful run of the Amazon AppFlow job, the curated data files are moved to the s3://consumer-databucket-<account-id>/marketo-leads-processed/ folder and Salesforce is updated with the leads. Additionally, all the original source files are moved from s3://consumer-databucket-<account-id>/marketo-leads-source/ to s3://consumer-databucket-<account-id>/marketo-leads-archive/.

  1. Review the updated data in Salesforce.

You will see newly created or updated leads created by Amazon AppFlow.

Clean up

To clean up the resources created as part of this post, delete the following resources:

  1. Delete the resources in the producer account:
    • Delete the producer S3 bucket content.
    • Delete the CloudFormation stack.
  2. Delete the resources in the consumer account:
    • Delete the consumer S3 bucket content.
    • Delete the CloudFormation stack.

Summary

In this post, we showed how you can support a cross-account model to exchange data between different partners with different SaaS integrations using Amazon AppFlow. You can expand this idea to support multiple target accounts.

For more information, refer to Simplifying cross-account access with Amazon EventBridge resource policies. To learn more about Amazon AppFlow, visit Amazon AppFlow.


About the authors

Ramakant Joshi is an AWS Solutions Architect, specializing in the analytics and serverless domain. He has a background in software development and hybrid architectures, and is passionate about helping customers modernize their cloud architecture.

Debaprasun Chakraborty is an AWS Solutions Architect, specializing in the analytics domain. He has around 20 years of software development and architecture experience. He is passionate about helping customers in cloud adoption, migration and strategy.

Suraj Subramani Vineet is a Senior Cloud Architect at Amazon Web Services (AWS) Professional Services in Sydney, Australia. He specializes in designing and building scalable and cost-effective data platforms and AI/ML solutions in the cloud. Outside of work, he enjoys playing soccer on weekends.