Tag Archives: Events

Modernize your legacy databases with AWS data lakes, Part 2: Build a data lake using AWS DMS data on Apache Iceberg

Post Syndicated from Shaheer Mansoor original https://aws.amazon.com/blogs/big-data/modernize-your-legacy-databases-with-aws-data-lakes-part-2-build-a-data-lake-using-aws-dms-data-on-apache-iceberg/

This is part two of a three-part series where we show how to build a data lake on AWS using a modern data architecture. This post shows how to load data from a legacy database (SQL Server) into a transactional data lake (Apache Iceberg) using AWS Glue. We show how to build data pipelines using AWS Glue jobs, optimize them for both cost and performance, and implement schema evolution to automate manual tasks. To review the first part of the series, where we load SQL Server data into Amazon Simple Storage Service (Amazon S3) using AWS Database Migration Service (AWS DMS), see Modernize your legacy databases with AWS data lakes, Part 1: Migrate SQL Server using AWS DMS.

Solution overview

In this post, we go over the process of building a data lake, providing the rationale behind the different decisions, and share best practices when building such a solution.

The following diagram illustrates the different layers of the data lake.

Overall Architecture

To load data into the data lake, AWS Step Functions can define a workflow, Amazon Simple Queue Service (Amazon SQS) can track the order of incoming files, and AWS Glue jobs and the Data Catalog can be used create the data lake silver layer. AWS DMS produces files and writes these files to the bronze bucket (as we explained in Part 1).

We can turn on Amazon S3 notifications and push the new arriving file names to an SQS first-in-first-out (FIFO) queue. A Step Functions state machine can consume messages from this queue to process the files in the order they arrive.

For processing the files, we need to create two types of AWS Glue jobs:

  • Full load – This job loads the entire table data dump into an Iceberg table. Data types from the source are mapped to an Iceberg data type. After the data is loaded, the job updates the Data Catalog with the table schemas.
  • CDC – This job loads the change data capture (CDC) files into the respective Iceberg tables. The AWS Glue job implements the schema evolution feature of Iceberg to handle schema changes such as addition or deletion of columns.

As in Part 1, the AWS DMS jobs will place the full load and CDC data from the source database (SQL Server) in the raw S3 bucket. Now we process this data using AWS Glue and save it to the silver bucket in Iceberg format. AWS Glue has a plugin for Iceberg; for details, see Using the Iceberg framework in AWS Glue.

Along with moving data from the bronze to the silver bucket, we also create and update the Data Catalog for further processing the data for the gold bucket.

The following diagram illustrates how the full load and CDC jobs are defined inside the Step Functions workflow.

Step Functions for loading data into the lake

In this post, we discuss the AWS Glue jobs for defining the workflow. We recommend using AWS Step Functions Workflow Studio, and setting up Amazon S3 event notifications and an SNS FIFO queue to receive the filename as messages.

Prerequisites

To follow the solution, you need the following prerequisites set up as well as certain access rights and AWS Identity and Access Management (IAM) privileges:

  • An IAM role to run Glue jobs
  • IAM privileges to create AWS DMS resources (this role was created in Part 1 of this series; you can use the same role here)
  • The AWS DMS job from Part 1 working and producing files for the source database on Amazon S3.

Create an AWS Glue connection for the source database

We need to create a connection between AWS Glue and the source SQL Server database so the AWS Glue job can query the source for the latest schema while loading the data files. To create the connection, follow these steps:

  1. On the AWS Glue console, choose Connections in the navigation pane.
  2. Choose Create custom connector.
  3. Give the connection a name and choose JDBC as the connection type.
  4. In the JDBC URL section, enter the following string and replace the name of your source database endpoint and database that was set up in Part 1: jdbc:sqlserver://{Your RDS End Point Name}:1433/{Your Database Name}.
  5. Select Require SSL connection, then choose Create connector.

Clue Connections

Create and configure the full load AWS Glue job

Complete the following steps to create the full load job:

  1. On the AWS Glue console, choose ETL jobs in the navigation pane.
  2. Choose Script editor and select Spark.
  3. Choose Start fresh and select Create script.
  4. Enter a name for the full load job and choose the IAM role (mentioned in the prerequisites) for running the job.
  5. Finish creating the job.
  6. On the Job details tab, expand Advanced properties.
  7. In the Connections section, add the connection you created.
  8. Under Job parameters, pass the following arguments to the job:
    1. target_s3_bucket – The silver S3 bucket name.
    2. source_s3_bucket – The raw S3 bucket name.
    3. secret_id – The ID of the AWS Secrets Manager secret for the source database credentials.
    4. dbname – The source database name.
    5. datalake-formats – This sets the data format to iceberg.

Glue Job Parameters

The full load AWS Glue job starts after the AWS DMS task reaches 100%. The job loops over the files located in the raw S3 bucket and processes them one at time. For each file, the job infers the table name from the file name and gets the source table schema, including column names and primary keys.

If the table has one or more primary keys, the job creates an equivalent Iceberg table. If the job has no primary key, the file is not processed. In our use case, all the tables have primary keys, so we enforce this check. Depending on your data, you might need to handle this scenario differently.

You can use the following code to process the full load files. To start the job, choose Run.

import sys, boto3, json
import boto3
import json
from awsglue.utils import getResolvedOptions
from pyspark.context import SparkContext
from awsglue.context import GlueContext
from awsglue.job import Job
from pyspark.sql import SparkSession

#Get the arguments passed to the script
args = getResolvedOptions(sys.argv, ['JOB_NAME',
                           'target_s3_bucket',
                           'secret_id',
                           'source_s3_bucket'])
dbname = "AdventureWorks"
schema = "HumanResources"

#Initialize parameters
target_s3_bucket = args['target_s3_bucket']
source_s3_bucket = args['source_s3_bucket']
secret_id = args['secret_id']
unprocessed_tables = []
drop_column_list = ['db', 'table_name', 'schema_name', 'Op', 'last_update_time']  # DMS added columns

#Helper Function: Get Credentials from Secrets Manager
def get_db_credentials(secret_id):
    secretsmanager = boto3.client('secretsmanager')
    response = secretsmanager.get_secret_value(SecretId=secret_id)
    secrets = json.loads(response['SecretString'])
    return secrets['host'], int(secrets['port']), secrets['username'], secrets['password']

#Helper Function: Load Iceberg table with Primary key(s)
def load_table(full_load_data_df, dbname, table_name):

    try:
        full_load_data_df = full_load_data_df.drop(*drop_column_list)
        full_load_data_df.createOrReplaceTempView('full_data')

        query = """
        CREATE TABLE IF NOT EXISTS glue_catalog.{0}.{1}
        USING iceberg
        LOCATION "s3://{2}/{0}/{1}"
        AS SELECT * FROM full_data
        """.format(dbname, table_name, target_s3_bucket)
        spark.sql(query)
        
        #Update Table property to accept Schema Changes
        spark.sql("""ALTER TABLE glue_catalog.{0}.{1} SET TBLPROPERTIES (
                      'write.spark.accept-any-schema'='true'
                    )""".format(dbname, table_name))
        
    except Exception as ex:
        print(ex)
        failed_table = {"table_name": table_name, "Reason": ex}
        unprocessed_tables.append(failed_table)
        
def get_table_key(host, port, username, password, dbname):
    
    jdbc_url = "jdbc:sqlserver://{0}:{1};databaseName={2}".format(host, port, dbname)
    
    connectionProperties = {
      "user" : username,
      "password" : password
    }
    
    spark.read.jdbc(url=jdbc_url, table='INFORMATION_SCHEMA.TABLE_CONSTRAINTS', properties=connectionProperties).createOrReplaceTempView("TABLE_CONSTRAINTS")
    spark.read.jdbc(url=jdbc_url, table='INFORMATION_SCHEMA.CONSTRAINT_COLUMN_USAGE', properties=connectionProperties).createOrReplaceTempView("CONSTRAINT_COLUMN_USAGE")
    df_table_pkeys = spark.sql("select c.TABLE_NAME, C.COLUMN_NAME as primary_key FROM TABLE_CONSTRAINTS T JOIN CONSTRAINT_COLUMN_USAGE C ON C.CONSTRAINT_NAME=T.CONSTRAINT_NAME WHERE T.CONSTRAINT_TYPE='PRIMARY KEY'")
    return df_table_pkeys


#Setup Spark configuration for reading and writing Iceberg tables
spark = (
    SparkSession.builder
    .config("spark.sql.extensions", "org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions")
    .config("spark.sql.catalog.glue_catalog", "org.apache.iceberg.spark.SparkCatalog")
    .config("spark.sql.catalog.glue_catalog.warehouse", "s3://{0}".format(dbname))
    .config("spark.sql.catalog.glue_catalog.catalog-impl", "org.apache.iceberg.aws.glue.GlueCatalog")
    .config("spark.sql.catalog.glue_catalog.io-impl", "org.apache.iceberg.aws.s3.S3FileIO")
    .getOrCreate()
)


#Initialize MSSQL credentials
host, port, username, password = get_db_credentials(secret_id)

#Initialize primary keys for all tables
df_table_pkeys = get_table_key(host, port, username, password, dbname)

#Read Full load csv files from s3
s3 = boto3.client('s3')
full_load_tables = s3.list_objects_v2(Bucket=source_s3_bucket, Prefix="raw/{0}/{1}".format(args['dbname'], args['schema']))

#Loop over files
for item in full_load_tables['Contents']:
    pkey_list = []
    table_name = item["Key"].split("/")[3].lower()
    print("Table name {0}".format(table_name))
    current_table_df = df_table_pkeys.where(df_table_pkeys.TABLE_NAME == table_name)

    # Only Process tables with at least 1 Primary key
    if not current_table_df.isEmpty():
        for i in current_table_df.collect():
            pkey_list.append(i["primary_key"])
    else:
        failed_table = {"table_name": table_name, "Reason": "No primary key"}
        unprocessed_tables.append(failed_table)
        # ToDo Handle these cases

    full_data_path = "s3://{0}/{1}".format(source_s3_bucket, item['Key'])
    full_load_data_df = (spark
                        .read
                        .option("header", True)
                        .option("inferSchema", True)
                        .option("recursiveFileLookup", "true")
                        .csv(full_data_path)
                        )

    primary_key = ",".join(pkey_list)

    if table_name not in unprocessed_tables:
        load_table(full_load_data_df, dbname, table_name)

When the job is complete, it creates the database and tables in the Data Catalog, as shown in the following screenshot.

Data lake silver layer data

Create and configure the CDC AWS Glue job

The CDC AWS Glue job is created similar to the full load job. As with the full load AWS Glue job, you need to use the source database connection and pass the job parameters with one additional parameter, cdc_file, which contains the location of the CDC file to be processed. Because a CDC file can contain data for multiple tables, the job loops over the tables in a file and loads the table metadata from the source table ( RDS column names).

If the CDC operation is DELETE, the job deletes the records from the Iceberg table. If the CDC operation is INSERT or UPDATE, the job merges the data into the Iceberg table.

You can use the following code to process the CDC files. To start the job, choose Run

import sys
import boto3
import json
from awsglue.utils import getResolvedOptions
from pyspark.context import SparkContext
from awsglue.context import GlueContext
from awsglue.job import Job
from pyspark.sql import SparkSession

# Get the arguments passed to the script
args = getResolvedOptions(sys.argv, ['JOB_NAME',
                           'target_s3_bucket',
                           'secret_id',
                           'source_s3_bucket',
                           'cdc_file'])
dbname = "AdventureWorks"
schema = "HumanResources"
target_s3_bucket = args['target_s3_bucket']
source_s3_bucket = args['source_s3_bucket']
secret_id = args['secret_id']
cdc_file = args['cdc_file']
unprocessed_tables = []
drop_column_list = ['db', 'table_name', 'schema_name', 'Op', 'last_update_time']  # DMS added columns
source_s3_cdc_file_key = "raw/AdventureWorks/cdc/" + cdc_file


# Helper Function: Get Credentials from Secrets Manager
def get_db_credentials(secret_id):
    secretsmanager = boto3.client('secretsmanager')
    response = secretsmanager.get_secret_value(SecretId=secret_id)
    secrets = json.loads(response['SecretString'])
    return secrets['host'], int(secrets['port']), secrets['username'], secrets['password']

# Helper Function: Column names from RDS
def get_table_colums(table, host, port, username, password, dbname):

    jdbc_url = "jdbc:sqlserver://{0}:{1};databaseName={2}".format(host, port, dbname)
    
    connectionProperties = {
      "user" : username,
      "password" : password
    }
    
    spark.read.jdbc(url=jdbc_url, table='INFORMATION_SCHEMA.COLUMNS', properties= connectionProperties).createOrReplaceTempView("TABLE_COLUMNS")
    columns = list((row.COLUMN_NAME) for (index, row) in spark.sql("select TABLE_NAME, TABLE_CATALOG, COLUMN_NAME from TABLE_COLUMNS where TABLE_NAME = '{0}' and TABLE_CATALOG = '{1}'".format(table, dbname)).select("COLUMN_NAME").toPandas().iterrows())
    return columns

# Helper Function: Get Colum names and datatypes from RDS
def get_table_colum_datatypes(table, host, port, username, password, dbname):

    jdbc_url = "jdbc:sqlserver://{0}:{1};databaseName={2}".format(host, port, dbname)
    
    connectionProperties = {
      "user" : username,
      "password" : password
    }
    
    spark.read.jdbc(url=jdbc_url, table='INFORMATION_SCHEMA.COLUMNS', properties= connectionProperties).createOrReplaceTempView("TABLE_COLUMNS")
    return spark.sql("select TABLE_NAME, COLUMN_NAME, DATA_TYPE from TABLE_COLUMNS WHERE TABLE_NAME ='{0}'".format(table))

# Helper Function: Setup the primary key condition
def get_iceberg_table_condition(database, tablename):
    
    jdbc_url = "jdbc:sqlserver://{0}:{1};databaseName={2}".format(host, port, database)
    
    connectionProperties = {
      "user" : username,
      "password" : password
    }
    
    spark.read.jdbc(url=jdbc_url, table='INFORMATION_SCHEMA.TABLE_CONSTRAINTS', properties=connectionProperties).createOrReplaceTempView("TABLE_CONSTRAINTS")
    spark.read.jdbc(url=jdbc_url, table='INFORMATION_SCHEMA.CONSTRAINT_COLUMN_USAGE', properties=connectionProperties).createOrReplaceTempView("CONSTRAINT_COLUMN_USAGE")
    
    condition = ''
    
    for key in spark.sql("select C.COLUMN_NAME FROM TABLE_CONSTRAINTS T JOIN CONSTRAINT_COLUMN_USAGE C ON C.CONSTRAINT_NAME=T.CONSTRAINT_NAME WHERE T.CONSTRAINT_TYPE='PRIMARY KEY' AND c.TABLE_NAME = '{0}'".format(table)).collect():
        condition += "target.{0} = source.{0} and".format(key.COLUMN_NAME)
    return condition[:-4]

    
# Read incoming data from Amazon S3
def read_cdc_S3(source_s3_bucket, source_s3_cdc_file_key):
    
    inputDf = (spark
                    .read
                    .option("header", False)
                    .option("inferSchema", True)
                    .option("recursiveFileLookup", "true")
                    .csv("s3://" + source_s3_bucket + "/" + source_s3_cdc_file_key)
                    )
    return inputDf

# Setup Spark configuration for reading and writing Iceberg tables
spark = (
    SparkSession.builder
    .config("spark.sql.extensions", "org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions")
    .config("spark.sql.catalog.glue_catalog", "org.apache.iceberg.spark.SparkCatalog")
    .config("spark.sql.catalog.glue_catalog.warehouse", "s3://{0}".format(target_s3_bucket))
    .config("spark.sql.catalog.glue_catalog.catalog-impl", "org.apache.iceberg.aws.glue.GlueCatalog")
    .config("spark.sql.catalog.glue_catalog.io-impl", "org.apache.iceberg.aws.s3.S3FileIO")
    .getOrCreate()
)

#Initialize MSSQL credentials
host, port, username, password = get_db_credentials(secret_id)

#Read the cdc file 
cdc_df = read_cdc_S3(source_s3_bucket, source_s3_cdc_file_key)

tables = cdc_df.toPandas()._c1.unique().tolist()

#Loop over tables in the cdc file
for table in tables:
    #Create dataframes for delets and for inserts and updates
    table_df_deletes = cdc_df.where((cdc_df._c1 == table) & (cdc_df._c0 == "D")).drop(cdc_df.columns[0], cdc_df.columns[1], cdc_df.columns[2], cdc_df.columns[3])
    table_df_upserts = cdc_df.where((cdc_df._c1 == table) & ((cdc_df._c0 == "I") | (cdc_df._c0 == "U"))).drop(cdc_df.columns[0], cdc_df.columns[1], cdc_df.columns[2], cdc_df.columns[3])
    
    #Update column names for the dataframes
    columns = get_table_colums(table, host, port, username, password, dbname) 
    selectExpr = [] 

    for column in columns: 
        selectExpr.append(cdc_df.where((cdc_df._c1 == table)).drop(cdc_df.columns[0], cdc_df.columns[1], cdc_df.columns[2], cdc_df.columns[3]).columns[columns.index(column)] + " as " + column)

    table_df_deletes = table_df_deletes.selectExpr(selectExpr) 
    table_df_upserts = table_df_upserts.selectExpr(selectExpr)
    
    #Process Deletes
    if table_df_deletes.count() > 0:
        
        print("Delete Triggered")
        table_df_deletes.createOrReplaceTempView('deleted_rows')
        
        sql_string = """MERGE INTO glue_catalog.{0}.{1} target
                        USING (SELECT * FROM deleted_rows) source
                        ON {2}
                        WHEN MATCHED 
                        THEN DELETE""".format(database, table.lower(), get_iceberg_table_condition(database, table.lower()))
        spark.sql(sql_string)
    
    if table_df_upserts.count() > 0:
        print("Upsert triggered")

        #Upsert Records when there are Schema Changes
        if len(table_df_upserts.columns) != len(columns):

            #Handle column deletes
            if len(table_df_upserts.columns) < len(columns):

                drop_columns = list(set(columns) - set(table_df_upserts.columns))

                for drop_column in drop_columns:
                    sql_string = """
                                    ALTER TABLE glue_catalog.{0}.{1}
                                    DROP COLUMN {2}""".format(dbname.lower(), table.lower(), drop_column)
                    spark.sql(sql_string)

            #Handle column additions
            elif len(table_df_upserts.columns) > len(columns):

                column_datatype_df = get_table_colum_datatypes(table, host, port, username, password, dbname)
                add_columns = list(set(table_df_upserts.columns) - set(columns))

                for add_column in add_columns:

                    #Set Iceberg data type
                    data_type = list((row.DATA_TYPE) for (index, row) in column_datatype_df.filter("COLUMN_NAME='{0}'".format(add_column)).select("DATA_TYPE").toPandas().iterrows())[0]

                    # Convert MSSQL Datatypes to Iceberg supported datatypes
                    if data_type.lower() in ["varchar", "char"]:
                        data_type = "string"

                    if data_type.lower() in ["bigint"]:
                        data_type = "long"

                    if data_type.lower() in ["array"]:
                        data_type = "list"

                    sql_string = """
                                    ALTER TABLE glue_catalog.{0}.{1}
                                    ADD COLUMN {2} {3}""".format(dbname.lower(), table.lower(), add_column, data_type)
                    spark.sql(sql_string)
                    
            #Create statement to update columns
            update_table_column_list = ""
            insert_column_list = ""
            columns = get_table_colums(table, host, port, username, password, dbname)             

            for column in columns:

                update_table_column_list+="""target.{0}=source.{0},""".format(column)
                insert_column_list+="""source.{0},""".format(column)

            table_df_upserts.createOrReplaceTempView('updated_rows')

            sql_string = """MERGE INTO glue_catalog.{0}.{1} target
                            USING (SELECT * FROM updated_rows) source
                            ON {2}
                            WHEN MATCHED 
                            THEN UPDATE SET {3} 
                            WHEN NOT MATCHED THEN INSERT ({4}) VALUES ({5})""".format(dbname.lower(), 
                                                                                      table.lower(), 
                                                                                      get_iceberg_table_condition(dbname.lower(), table.lower()), 
                                                                                      update_table_column_list.rstrip(","), 
                                                                                      ",".join(columns), 
                                                                                      insert_column_list.rstrip(","))

            spark.sql(sql_string)

    
print("CDC job complete")

The Iceberg MERGE INTO syntax can handle cases where a new column is added. For more details on this feature, see the Iceberg MERGE INTO syntax documentation. If the CDC job needs to process many tables in the CDC file, the job can be multi-threaded to process the file in parallel.


Configure EventBridge notifications, SQS queue, and Step Functions state machine

You can use EventBridge notifications to send notifications to EventBridge when certain events occur on S3 buckets, such as when new objects are created and deleted. For this post, we’re interested in the events when new CDC files from AWS DMS arrive in the bronze S3 bucket. You can create event notifications for new objects and insert the file names into an SQS queue. A Lambda function within Step Functions would consume from the queue, extract the file name, start a CDC Glue job, and pass the file name as a parameter to the job.

AWS DMS CDC files contain database insert, update, and delete statements. We need to process these in order, so we use an SQS FIFO queue, which preserves the order of messages in which they arrive. You can also configure Amazon SQS to set a time to live (TTL); this parameter defines how long a message stays in the queue before it expires.

Another important parameter to consider when configuring an SQS queue is the message visibility timeout value. While a message is being processed, it disappears from the queue to make sure that the message isn’t consumed by multiple consumers (AWS Glue jobs in our case). If the message is consumed successfully, it should be deleted from the queue before the visibility timeout. However, if the visibility timeout expires and the message isn’t deleted, the message reappears in the queue. In our solution, this timeout must be greater than the time it takes for the CDC job to process a file.

Lastly, we recommend using Step Functions to define a workflow for handling the full load and CDC files. Step Functions has built-in integrations to other AWS services like Amazon SQS, AWS Glue, and Lambda, which makes it a good candidate for this use case.

The Step Functions state machine starts with checking the status of the AWS DMS task. The AWS DMS tasks can be queried to check the status of the full load, and we check the value of the parameter FullLoadProgressPercent. When this value gets to 100%, we can start processing the full load files. After the AWS Glue job processes the full load files, we start polling the SQS queue to check the size of the queue. If the queue size is greater than 0, this means new CDC files have arrived and we can start the AWS Glue CDC job to process these files. The AWS Glue jobs processes the CDC files and deletes the messages from the queue. When the queue size reaches 0, the AWS Glue job exits and we loop in the Step Functions workflow to check the SQS queue size.

Because the Step Functions state machine is supposed to run indefinitely, it’s good to keep in mind that there will be service limits you need to adhere to. Namely, the maximum runtime, which is 1 year, and maximum run history size, i.e., state transitions or events for a state machine which is 25,000. We recommend adding an additional step at the end to check if either of these conditions are being met to stop the current state machine run and start a new one.

The following diagram illustrates how you can use Step Functions state machine history size to monitor and start a new Step Functions state machine run.

Step Functions Workflow

Configure the pipeline

The pipeline needs to be configured to address cost, performance, and resilience goals. You might want a pipeline that can load fresh data into the data lake and make it available quickly, and you might also want to optimize costs by loading large chunks of data into the data lake. At the same time, you should make the pipeline resilient and be able to recover in case of failures. In this section, we cover the different parameters and recommended settings to achieve these goals.

Step Functions is designed to process incoming AWS DMS CDC files by running AWS Glue jobs. AWS Glue jobs can take a couple of minutes to boot up, and when they’re running, it’s efficient to process large chunks of data. You can configure AWS DMS to write CSV files to Amazon S3 by configuring the following AWS DMS task parameters:

  • CdcMaxBatchInterval – Defines the maximum time limit AWS DMS will wait before writing a batch to Amazon S3
  • CdcMinFileSize – Defines the minimum file size AWS DMS will write to Amazon S3

Whichever condition is met first will invoke the write operation. If you want to prioritize data freshness, you should have a short CdcMaxBatchInterval value (10 seconds) and a small CdcMinFileSize value (1–5 MB). This will result in many small CSV files being written to Amazon S3 and will invoke a lot of AWS Glue jobs to process the data, making the extract, transform, and load (ETL) process faster. If you want to optimize costs, you should have a moderate CdcMaxBatchInterval (minutes) and a large CdcMinFileSize value (100–500 MB). In this scenario, we start a few AWS Glue jobs that will process large chunks of data, making the ETL flow more efficient. In a real-world use case, the required values for these parameters might fall somewhere that’s a good compromise between throughput and cost. You can configure these parameters when creating a target endpoint using the AWS DMS console, or by using the create-endpoint command in the AWS Command Line Interface (AWS CLI).

For the full list of parameters, see Using Amazon S3 as a target for AWS Database Migration Service.

Choosing the right AWS Glue worker types for the full load and CDC jobs is also crucial for performance and cost optimization. The AWS Glue (Spark) workers range from G1X to G8X, which have an increasing number of data processing units (DPUs). Full load files are usually much larger in size compared to CDC files, and therefore it’s more cost- and performance-effective to select a larger worker. For CDC files, it would be more cost-effective to select a smaller worker because files sizes are smaller.

You should design the Step Functions state machine in such a way that if anything fails, the pipeline can be redeployed after repair and resume processing from where it left off. One important parameter here is TTL for the messages in the SQS queue. This parameter defines how long a message stays in the queue before expiring. In case of failures, we want this parameter to be long enough for us to deploy a fix. Amazon SQS has a maximum of 14 days for a message’s TTL. We recommend setting this to a large enough value to minimize messages being expired in case of pipeline failures.

Clean up

Complete the following steps to clean up the resources you created in this post:

  1. Delete the AWS Glue jobs:
    1. On the AWS Glue console, choose ETL jobs in the navigation pane.
    2. Select the full load and CDC jobs and on the Actions menu, choose Delete.
    3. Choose Delete to confirm.
  2. Delete the Iceberg tables:
    1. On the AWS Glue console, under Data Catalog in the navigation pane, choose Databases.
    2. Choose the database in which the Iceberg tables reside.
    3. Select the tables to delete, choose Delete, and confirm the deletion.
  3. Delete the S3 bucket:
    1. On the Amazon S3 console, choose Buckets in the navigation pane.
    2. Choose the silver bucket and empty the files in the bucket.
    3. Delete the bucket.

Conclusion

In this post, we showed how to use AWS Glue jobs to load AWS DMS files into a transactional data lake framework such as Iceberg. In our setup, AWS Glue provided highly scalable and simple-to-maintain ETL jobs. Furthermore, we share a proposed solution using Step Functions to create an ETL pipeline workflow, with Amazon S3 notifications and an SQS queue to capture newly arriving files. We shared how to design this system to be resilient towards failures and to automate one of the most time-consuming tasks in maintaining a data lake: schema evolution.

In Part 3, we will share how to process the data lake to create data marts.


About the Authors

Shaheer Mansoor is a Senior Machine Learning Engineer at AWS, where he specializes in developing cutting-edge machine learning platforms. His expertise lies in creating scalable infrastructure to support advanced AI solutions. His focus areas are MLOps, feature stores, data lakes, model hosting, and generative AI.

Anoop Kumar K M is a Data Architect at AWS with focus in the data and analytics area. He helps customers in building scalable data platforms and in their enterprise data strategy. His areas of interest are data platforms, data analytics, security, file systems and operating systems. Anoop loves to travel and enjoys reading books in the crime fiction and financial domains.

Sreenivas Nettem is a Lead Database Consultant at AWS Professional Services. He has experience working with Microsoft technologies with a specialization in SQL Server. He works closely with customers to help migrate and modernize their databases to AWS.

AWS Weekly Roundup: Agentic workflows, Amazon Transcribe, AWS Lambda insights, and more (October 21, 2024)

Post Syndicated from Antje Barth original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-agentic-workflows-amazon-transcribe-aws-lambda-insights-and-more-october-21-2024/

Agentic workflows are quickly becoming a cornerstone of AI innovation, enabling intelligent systems to autonomously handle and refine complex tasks in a way that mirrors human problem-solving. Last week, we launched Serverless Agentic Workflows with Amazon Bedrock, a new short course developed in collaboration with Dr. Andrew Ng and DeepLearning.AI.

Serverless Agentic Workflows with Amazon Bedrock

This hands-on course, taught by my colleague Mike Chambers, teaches how to build serverless agents that can handle complex tasks without the hassle of managing infrastructure. You will learn everything you need to know about integrating tools, automating workflows, and deploying responsible agents with built-in guardrails on Amazon Web Services (AWS) with Amazon Bedrock. The hands-on labs provided with the course let you apply your knowledge directly in an AWS environment, hosted by AWS Partner Vocareum. Find more information and enroll for free on the DeepLearning.AI course page.

Now, let’s turn our attention to other exciting news in the AWS universe from last week.

Last week’s launches
Here are some launches that got my attention:

Amazon Transcribe now supports streaming transcription in 30 additional languagesAmazon Transcribe has expanded its support to include 30 additional languages, bringing the total number of supported languages to 54. This enhancement helps you reach a broader global audience and improves accessibility across various industries, including contact centers, broadcasting, and e-learning. The expanded language support allows for more efficient content moderation, improved agent productivity, and automatic subtitling for live events and meetings.

AWS Lambda console now surfaces key function insights and supports real-time log analytics – The AWS Lambda console now features a built-in Amazon CloudWatch Metrics Insights dashboard and supports CloudWatch Logs Live Tail, providing instant visibility into critical function metrics and real-time log streaming. You can now identify and troubleshoot errors or performance issues for your Lambda functions without leaving the console, as well as view and analyze logs in real time as they become available. You can reduce context switching and accelerate the development and troubleshooting processes for serverless applications. Check out the launch post for more details.

Amazon Bedrock Model Evaluation now supports evaluating custom model import models – You can now evaluate custom models you’ve imported to Amazon Bedrock using the model evaluation feature. This helps you to complete the full cycle of selecting, customizing, and evaluating models before deploying them. To evaluate an imported model, select the custom model from the list of models to evaluate in the model selector tool when creating an evaluation job.

Amazon Q in AWS Supply Chain – You can now use Amazon Q, an interactive AI assistant, to analyze your supply chain data in AWS Supply Chain and get insights to operate your supply chain more efficiently. Amazon Q can answer your supply chain questions by diving into your data. This reduces the time spent searching for information and streamlines finding answers to improve your supply chain operations.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS news
Here are some additional news items and posts that you might find interesting:

New Amazon OpenSearch Service YouTube channel – The channel offers bite-sized tutorials, curated content, and organized playlists on topics such as log analytics, semantic search, vector databases, and operational best practices. You can also provide feedback to influence future channel content and the OpenSearch Service roadmap. Check out the launch post for more details and subscribe to the Amazon OpenSearch Service YouTube channel.

Deploying Generative AI Applications with NVIDIA NIM Microservices on Amazon Elastic Kubernetes Service (Amazon EKS) – This post shows you how to use Amazon EKS to orchestrate the deployment of pods containing NVIDIA NIM microservices, to enable quick-to-setup and optimized large-scale large language model (LLM) inference on Amazon EC2 G5 instances. It also demonstrates how to scale (both pod and cluster) by monitoring for custom metrics through Prometheus, and how you can load balance using an Application Load Balancer.

Instant Well-Architected CDK Resources with Solutions Constructs Factories – You can now create well-architected AWS resources such as Amazon Simple Storage Service (Amazon S3) buckets and AWS Step Functions state machines with a single function call using the new AWS Solutions Constructs Factories. These factories handle all the best practices configuration for you while still allowing customization. Try using a Constructs factory the next time you need to deploy one of the supported resources.

Upcoming AWS events
Check your calendars and sign up for these AWS events:

AWS GenAI LoftsAWS GenAI LoftsAWS GenAI Lofts are about more than just the tech, they bring together startups, developers, investors, and industry experts. Whether you’re looking to gain deep insights, or get your questions answered by generative AI pros, our GenAI Lofts have you covered and provide everything you need to start building your next innovation. Join events in London (through October 25), Seoul (October 30–November 6), São Paulo (through November 20), and Paris (through November 25).

AWS Community DaysAWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Malta (November 8), Chile (November 9), and Kochi, India (December 14).

AWS re:Invent 2024AWS re:InventRegistration is now open for the annual tech extravaganza, taking place December 2–6 in Las Vegas. At re:Invent 2024, you’ll get a front row seat to hear real stories from customers and AWS leaders about navigating pressing topics, such as generative AI. Learn about new product launches, watch demos, and get behind-the-scenes insights during five headline-making keynotes.

You can browse all upcoming in-person and virtual events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Antje

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

Amazon Q Developer Code Challenge

Post Syndicated from Aaron Sempf original https://aws.amazon.com/blogs/devops/amazon-q-developer-code-challenge/

Amazon Q Developer is a generative artificial intelligence (AI) powered conversational assistant that can help you understand, build, extend, and operate AWS applications. You can ask questions about AWS architecture, your AWS resources, best practices, documentation, support, and more.

With Amazon Q Developer in your IDE, you can write a comment in natural language that outlines a specific task, such as, “Upload a file with server-side encryption.” Based on this information, Amazon Q Developer recommends one or more code snippets directly in the IDE that can accomplish the task. You can quickly and easily accept the top suggestions (tab key), view more suggestions (arrow keys), or continue writing your own code.

However, Amazon Q Developer in the IDE is more than just a code completion plugin. Amazon Q Developer is a generative AI (GenAI) powered assistant for software development that can be used to have a conversation about your code, get code suggestions, or ask questions about building software. This provides the benefits of collaborative paired programming, powered by GenAI models that have been trained on billions of lines of code, from the Amazon internal code-base and publicly available sources.

The challenge

At the 2024 AWS Summit in Sydney, an exhilarating code challenge took center stage, pitting a Blue Team against a Red Team, with approximately 10 to 15 challengers in each team, in a battle of coding prowess. The challenge consisted of 20 tasks, starting with basic math and string manipulation, and progressively escalating in difficulty to include complex algorithms and intricate ciphers.

The Blue Team had a distinct advantage, leveraging the powerful capabilities of Amazon Q Developer, the most capable generative AI-powered assistant for software development. With Q Developer’s guidance, the Blue Team navigated increasingly complex tasks with ease, tapping into Q Developer’s vast knowledge base and problem-solving abilities. In contrast, the Red Team competed without assistance, relying solely on their own coding expertise and problem-solving skills to tackle daunting challenges.

As the competition unfolded, the two teams battled it out, each striving to outperform the other. The Blue Team’s efficient use of Amazon Q Developer proved to be a game-changer, allowing them to tackle the most challenging tasks with remarkable speed and accuracy. However, the Red Team’s sheer determination and technical prowess kept them in the running, showcasing their ability to think outside the box and devise innovative solutions.

The culmination of the code challenge was a thrilling finale, with both teams pushing the boundaries of their skills and ultimately leaving the audience in a state of admiration for their remarkable achievements.

Graph of elapsed time of teams in the AWS Sydney Summit code challenge

The graph shows the average completion time in which Team Blue “Q Developer” completed more questions across the board in less time than Team Red “Solo Coder”. Within the 1-hour time limit, Team Blue got all the way to Question 19, whereas Team Red only got to Question 16.

There are some assumptions and validations. People who consider themselves very experienced programmers were encouraged to choose team Red and not use AI, to test themselves against team Blue, those using AI. The code challenges were designed to test the output of applying logic. They were specifically designed to be passable without the use of Amazon Q Developer, to test the optimization of writing logical code with Amazon Q Developer. As a result, the code tasks worked well with Amazon Q Developer due to the nature of and underlying training of Amazon Q Developer models. Many people who attended the event were not Python Programmers (we constrained the challenge to Python only), and walked away impressed at how much of the challenge they could complete.

As an example of one of the more complex questions competitors were given to solve was:

Implement the rail fence cipher.
In the Rail Fence cipher, the message is written downwards on successive "rails" of an imaginary fence, then moving up when we get to the bottom (like a zig-zag). Finally the message is then read off in rows.

For example, using three "rails" and the message "WE ARE DISCOVERED FLEE AT ONCE", the cipherer writes out: 

W . . . E . . . C . . . R . . . L . . . T . . . E
. E . R . D . S . O . E . E . F . E . A . O . C .
. . A . . . I . . . V . . . D . . . E . . . N . .

Then reads off: WECRLTEERDSOEEFEAOCAIVDEN

Given variable a. Use a three-rail fence cipher so that result is equal to the decoded message of variable a.

The questions were both algorithmic and logical in nature, which made them great for testing conversational natural language capability to solve questions using Amazon Q Developer, or by applying one’s own logic to write code to solve the question.

Top scoring individual per team:

Total Questions Complete individual time (min)
With Q Developer (Blue Team) 19 30.46
Solo Coder (Red Team) 16 58.06

By comparing the top two competitors, and considering the solo coder was a highly experienced programmer versus the top Q Developer coder, who was a relatively new programmer not familiar with Python, you can see the efficiency gain when using Q Developer as an AI peer programmer. It took the entire 60 minutes for the solo coder to complete 16 questions, whereas the Q Developer coder got to the final question (Question 20, incomplete) in half of the time.

Summary

Integrating advanced IDE features and adopting paired programming have significantly improved coding efficiency and quality. However, the introduction of Amazon Q Developer has taken this evolution to new heights. By tapping into Q Developer’s vast knowledge base and problem-solving capabilities, the Blue Team was able to navigate complex coding challenges with remarkable speed and accuracy, outperforming the unassisted Red Team. This highlights the transformative impact of leveraging generative AI as a collaborative pair programmer in modern software development, delivering greater efficiency, problem-solving, and, ultimately, higher-quality code. Get started with Amazon Q Developer for your IDE by installing the plugin and enabling your builder ID today.

About the authors:

Aaron Sempf

Aaron Sempf is Next Gen Tech Lead for the AWS Partner Organization in Asia-Pacific and Japan. With over twenty years in software engineering and distributed system, he focuses on solving for large scale complex integration and event driven systems. In his spare time, he can be found coding prototypes for autonomous robots, IoT devices, distributed solutions and designing Agentic Architecture patterns for GenAI assisted business automation.

Paul Kukiel

Paul Kukiel

Paul Kukiel is a Senior Solutions Architect at AWS. With a background of over twenty years in software engineering, he particularly enjoys helping customers build modern, API Driven software architectures at scale. In his spare time, he can be found building prototypes for micro front ends and event driven architectures.

Command with Confidence: Insights from Andrew Bustamante

Post Syndicated from Emma Burdett original https://blog.rapid7.com/2024/08/28/command-with-confidence-insights-from-andrew-bustamante/

Command with Confidence: Insights from Andrew Bustamante

At the recent Take Command Summit, former CIA intelligence officer and US Air Force combat veteran Andrew Bustamante shared valuable tools, tactics, and techniques from elite intelligence agencies with Rapid7’s Americas Field CTO Jeffrey Gardner in an informal chat. His session, “Command with Confidence,” offered cybersecurity professionals insights to enhance their security strategies with clarity and confidence.

Key Takeaways:

  1. The Four C’s Framework: Bustamante introduced the “Four C’s” framework—consideration, consistency, collaboration, and control. This structured approach is designed to build rapport, ensure consistent performance, and effectively lead teams by taking proactive control.
  2. Goal Setting Techniques: Highlighting a three-step framework for goal setting, Bustamante emphasized starting with SMART goals, then stretching them, and finally aiming for “scary goals” to push boundaries and achieve exceptional outcomes.
  3. The Power of Soft Skills and Persuasion: Bustamante explained how persuasion is rooted in emotional connections rather than logical arguments. By assessing individuals and understanding their emotional triggers, professionals can create compelling narratives that drive action. These soft skills are critical in building effective teams and leading security projects successfully.

“Consideration, consistency, collaboration, and control—these are the pillars of effective leadership and influence. Mastering these can make you unstoppable in any professional environment.” – Andrew Bustamante

Survey Insight: We surveyed our attendees on the importance of soft skills versus technical skills in new security projects. The results showed:

  • 37.5% agree and 34.38% strongly agree that the security community prioritizes technical skills over soft skills.

Ransomware attacks are a significant threat, but with the right strategies and proactive measures, organizations can enhance their defenses and build resilience. To dive deeper into these strategies and hear more from the experts, watch the full video from the Rapid7 Take Command Summit.

Key Takeaways From The Take Command Summit: Navigating New SEC Cybersecurity Disclosure Rules

Post Syndicated from Emma Burdett original https://blog.rapid7.com/2024/08/23/key-takeaways-from-the-take-command-summit-navigating-new-sec-cybersecurity-disclosure-rules/

Key Takeaways From The Take Command Summit: Navigating New SEC Cybersecurity Disclosure Rules

Understanding and complying with the new SEC Cybersecurity Disclosure Rules is a daunting task for many organizations. The Rapid7 Take Command Summit provided an in-depth look at these regulations, offering valuable guidance for cybersecurity professionals.

Here are three key takeaways from the session that are crucial for ensuring compliance and enhancing your organization’s cybersecurity posture.

1. Understand Materiality and Disclosure Requirements

One of the most critical aspects of the new SEC rules is determining the materiality of a cybersecurity incident. Kyra Ayo Caros, Director, Corporate Securities & Compliance at Rapid7  said, “materiality in this context is what would be material for investors to know…what sort of incident would your stakeholders or stockholders need to know about?” This involves assessing the incident’s impact on business operations and financial results. Companies must disclose material incidents within four days of determining their significance, highlighting the need for a robust incident response and evaluation process.

2. Foster Cross-Departmental Collaboration

Effective compliance with SEC rules requires coordination across various departments. Legal Counsel, Cybersecurity Services Group, Venable LLP Harley Geiger emphasized the importance of involving security, legal, and communications teams early in the process to meet disclosure requirements effectively. “Companies should ensure that security, legal, and communications teams are part of the process early on to collaborate on the most effective way of meeting these disclosure requirements.” This collaboration ensures that all relevant information is accurately assessed and reported.

3. Build a Comprehensive Cybersecurity Risk Management Program

The SEC rules also mandate annual disclosure of cybersecurity risk management processes and the role of senior management in overseeing these efforts. Organizations need to describe how they integrate cybersecurity into their overall risk management and governance framework. “It’s crucial to provide an accurate snapshot of your cybersecurity processes and management’s oversight to ensure investor trust,” said Ayo Caros. Ensuring these disclosures are accurate and reflect actual practices is vital for maintaining transparency and compliance.

57% of our post event survey respondents found the complexity and scope of regulations to be the most inhibiting factor in abiding by the SEC Cybersecurity Disclosure Rules. Navigating these intricate requirements poses a significant challenge, often leading to compliance difficulties.

The SEC Cybersecurity Disclosure Rules require a strategic and collaborative approach to ensure compliance and transparency. Understanding materiality, fostering cross-departmental collaboration, and building a comprehensive cybersecurity risk management program are essential steps. For a deeper dive into these strategies and expert insights, click here to watch the full video from the Rapid7 Take Command Event.

Key Takeaways From The Take Command Summit: Enhancing Cybersecurity Culture

Post Syndicated from Emma Burdett original https://blog.rapid7.com/2024/08/16/key-takeaways-from-the-take-command-summit-enhancing-cybersecurity-culture/

Key Takeaways From The Take Command Summit: Enhancing Cybersecurity Culture

Building a resilient cybersecurity culture is crucial in today’s digital landscape. The recent Rapid7 Take Command Summit session titled “Commander in Chief: Enhancing Cybersecurity Culture” offered valuable insights into fostering a strong security mindset within organizations.

Here are three key takeaways from the discussion that every cybersecurity professional should consider.

1. Align Security Objectives with Business Goals: Jaya Baloo, Chief Security Officer at Rapid7, emphasized the importance of aligning security goals with company objectives. “I rarely disjoint what needs to be done for security from the company’s core values and core business.” By integrating security initiatives with overall business goals, organizations can ensure that security measures receive the necessary support and resources.

2. Foster Empathy and Inclusion: Cultivating a cybersecurity culture that values empathy and inclusion is vital. Sofia Dozier, who leads Diversity, Equity, and Inclusion at Rapid7, highlighted the importance of understanding diverse perspectives within the workforce. “Empathy means putting yourself in someone else’s shoes to understand their experience.” By promoting inclusive behaviors, organizations can create a supportive environment where all employees are committed to security.

3. Navigate Complex Regulations with Clarity: A significant challenge for many organizations is navigating the intricate SEC Cybersecurity Disclosure Rules. According to a post summit survey of attendees, 57% of respondents find the complexity and scope of regulations to be the most inhibiting factor in compliance. Baloo stressed the importance of transparency and honesty in security practices, warning against the dangers of “lying by omission” due to fear of repercussions.

Enhancing cybersecurity culture requires aligning security with business goals, fostering empathy and inclusion, and navigating complex regulations transparently. “Culture eats strategy for breakfast,” Baloo said, emphasizing the critical role of a strong security culture in achieving cybersecurity success.

To delve deeper into these strategies and hear more expert insights, click here to watch the full video from Rapid7’s Take Command Summit.

Black Hat 2024: Key Takeaways and Industry Trends

Post Syndicated from Ryan Blanchard original https://blog.rapid7.com/2024/08/14/black-hat-2024-key-takeaways-and-industry-trends/

Black Hat 2024: Key Takeaways and Industry Trends

What a week! As Hacker Summer camp shifts into the rearview, it’s time to take a moment to reflect on the week, what we learned and the people we had the pleasure of meeting while out in Las Vegas. As is always the case at Black Hat 2024, the cybersecurity community was buzzing with the latest innovations and insights from their favorite vendors, industry speakers and training sessions. There was no shortage of information covered throughout the week, and with the sheer volume of it, it can be hard to catch everything going on. In this post I am going to do my part by attempting to summarize some of the key themes and takeaways from the event. So, with that, let’s get right to it.

  1. The rise of advanced threats: AI and machine learning at the forefront. One of the most striking themes at Black Hat 2024 was the sophistication of modern cyber threats. This year, sessions highlighted how attackers are leveraging artificial intelligence (AI) and machine learning (ML) to lower the barrier to entry, increase the scale and impact of attacks and circumvent traditional controls. From deepfake technology used in phishing schemes to AI-driven automated attacks, the industry is witnessing a new era of cyber threats that require equally advanced defensive strategies and continuous learning to ensure security teams keep pace with emerging trends and threat vectors.
  2. Zero trust and identity: the gradual shift towards never trust, always verify. Zero Trust was a major focal point at this year’s event. Experts and vendors alike emphasized the importance of adopting a Zero Trust approach to cybersecurity. This model, which operates on the principle of “never trust, always verify,” aims to minimize trust within and outside the network. The shift towards Zero Trust reflects the growing need for more robust security frameworks that can handle today’s complex threat environment.
  3. Software supply chain security: extending your defense beyond the perimete. Software supply chain attacks were a hot topic, underscoring the need for organizations to extend their security measures beyond their immediate environment. Black Hat 2024 reinforced the importance of securing not just your own systems but also those of your vendors, partners and the software dependencies that modern applications consist of. Discussions centered on strategies for improving supply chain resilience, shifting security visibility and gates earlier on in the development lifecycle and the role of continuous monitoring in mitigating these risks over time.
  4. Emerging technologies: navigating the new cybersecurity landscape. Black Hat 2024 showcased numerous emerging technologies and their implications for cybersecurity. Sessions explored the security challenges associated with Generative AI, blockchain, the Internet of Things (IoT) and Quantum Computing. As these technologies evolve, they bring both new opportunities and new risks, making it crucial for security professionals to stay informed and prepared.
  5. Training and awareness: building a culture of security. Many sessions emphasized the critical role of security training and awareness programs. With human error often cited as a leading cause of security incidents, organizations are increasingly focusing on educating their employees and fostering a culture of security awareness. Training programs that address current threats and promote best practices are becoming integral to comprehensive security strategies.

Keynote sessions did not disappoint

The keynote sessions at Black Hat are always one of my personal favorite parts, and this year was no exception. While there were a number of sessions I found insightful and well worth the watch, one in particular that stood out was Thursday’s Fireside chat with Moxie Marlinspike, the Founder of Signal, and Jeff Moss, the Founder of Black Hat and member of the U.S. Department of Homeland Security Advisory Council. During the session they covered a range of topics, but chief among them was the future of privacy and the balance between privacy and security.

Product launches: Surface Command and Exposure Command unveiled

Beyond rich discussions and cutting-edge presentations, we made some significant waves with the launch of Surface Command and Exposure Command, two exciting new product offerings designed to unify your attack surface and deliver effective hybrid risk management. We covered these new products a little more in-depth here, but to recap:

Surface Command: unifying your attack surface

Surface Command offers a unified view of both internal and external attack surfaces, breaking down data silos and providing a comprehensive picture of your environment. This tool helps organizations identify and address vulnerabilities more effectively.

Exposure Command: prioritizing critical threats with precision

Exposure Command extends these capabilities by enriching asset data with high-fidelity risk context, enabling teams to prioritize and address the most critical threats with greater precision.

These launches are a testament to Rapid7’s commitment to advancing cybersecurity and providing our customers with the tools they need to stay ahead of potential threats, and represent the next chapter in our mission to enable security teams to take command of their attack surface.

What’s Next for Rapid7?

Black Hat 2024 was a microcosm of the dynamic and rapidly evolving nature of the cybersecurity landscape. The insights gained and the innovations showcased will undoubtedly influence the industry’s approach to security in the coming years. As we move forward, the lessons from Black Hat and the invaluable direct feedback will inform our strategy and drive the development of new capabilities to meet the ever-changing demands of our customers and the industry at large.

As we wrap up our experiences from Black Hat 2024, it’s clear that the cybersecurity landscape is evolving rapidly, with new threats and technologies shaping the way we approach security. The insights gained from the event, along with the direct feedback from industry peers, will be instrumental in guiding our strategy at Rapid7. We’re excited to continue innovating and leading the charge in helping organizations take command of their attack surfaces. Stay tuned as we build on these insights to deliver even more powerful solutions in the coming months.

Key Takeaways From The Take Command Summit: Unlocking Security Success

Post Syndicated from Emma Burdett original https://blog.rapid7.com/2024/08/09/key-takeaways-from-the-take-command-summit-unlocking-security-success/

Key Takeaways From The Take Command Summit: Unlocking Security Success

As cybersecurity threats continue to evolve, so must our defenses. The recent Rapid7 Take Command Summit provided invaluable insights into preparing for, responding to, and recovering from ransomware attacks. Here are three essential takeaways from the session, “Before, During, & After Ransomware Attacks,” that every cybersecurity professional should consider.

1. Proactive Defense is Crucial: Fortify your defenses before an attack happens.. According to the panel, comprehensive security measures such as regular patching, network segmentation, and user training are vital. Implementing endpoint detection and response solutions can significantly reduce vulnerabilities. Eddie Bobritsky said, “prevention is always coming before detection and response. Investing in proactive measures is crucial.”

2. Swift Decision-Making During an Attack: During an attack, immediate and decisive action is paramount. Establishing clear protocols and communication channels can mitigate damage effectively. The panel highlighted the importance of isolating infected systems and restricting network access to contain the threat. Robert Knapp said, “swift decision-making is key to minimizing impact and ensuring a successful investigation.”

3. Building Resilience After an Attack: Recovery is a multifaceted effort. Conducting thorough forensic analysis to identify the root causes of the attack and implementing robust data backup and recovery processes are essential steps. Lonnie Best said, “building resilience against the recurrence of ransomware attacks requires proactive security measures and regular security assessments.”

Key Statistics

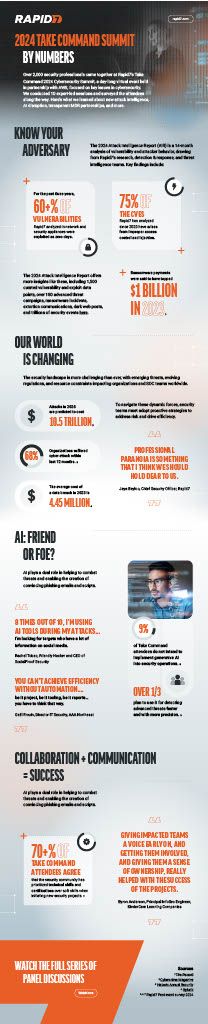
  • 65% of organizations impacted by ransomware in 2023 faced more than 6 days of downtime.
  • Ransomware payments were said to have topped $1 billion in 2023.
  • Rapid7 tracked 5600 reported ransomware cases between January 2023 and February 2024.

No matter how much you invest in the before stage, it will always be cheaper than dealing with it afterwards.” – Eddy Bobritsky, Senior Director, Product Management, Rapid7

Ransomware attacks are a significant threat, but with the right strategies and proactive measures, organizations can enhance their defenses and build resilience. To dive deeper into these strategies and hear more from the experts, watch the full video from the Rapid7 Take Command Summit.

 CSTA 2024: What happened in Las Vegas

Post Syndicated from James Robinson original https://www.raspberrypi.org/blog/csta-2024/

About three weeks ago, a small team from the Raspberry Pi Foundation braved high temperatures and expensive coffees (and a scarcity of tea) to spend time with educators at the CSTA Annual Conference in Las Vegas.

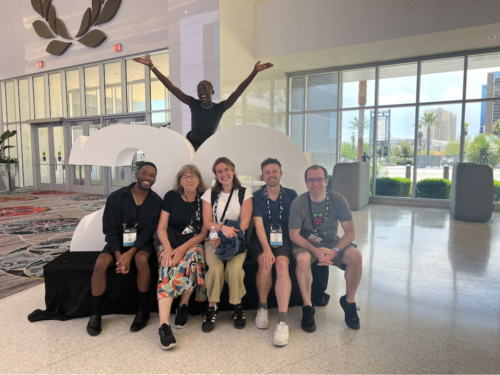
A team of 6 educators inside a conference hall.

With thousands of attendees from across the US and beyond participating in engaging workshops, thought-provoking talks, and visiting the fantastic expo hall, the CSTA conference was an excellent opportunity for us to connect with and learn from educators.

Meeting educators & sharing resources

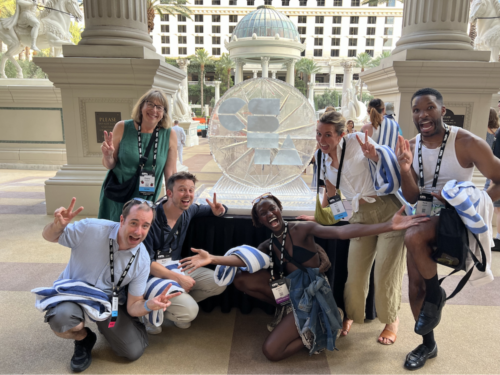
Our hope for the conference week was to meet and learn from as many different educators as possible, and we weren’t disappointed. We spoke with a wide variety of teachers, school administrators, and thought leaders about the progress, successes, and challenges of delivering successful computer science (CS) programs in the US (more on this soon). We connected and reconnected with so many educators at our stand, gave away loads of stickers… and we even gave away a Raspberry Pi Pico to one lucky winner each day.

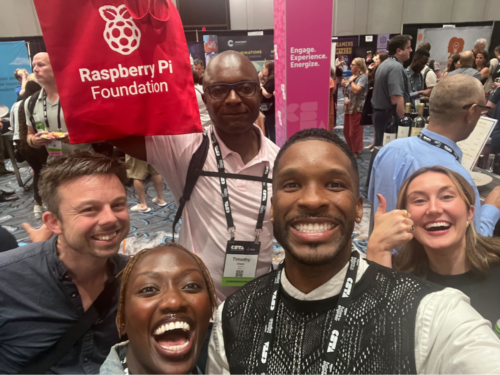
A group of educators taking a selfie at a conference.
The team with one of the winners of a Raspberry Pi Pico

As well as learning from hundreds of educators throughout the week, we shared some of the ways in which the Foundation supports teachers to deliver effective CS education. Our team was on hand to answer questions about our wide range of free learning materials and programs to support educators and young people alike. We focused on sharing our projects site and all of the ways educators can use the site’s unique projects pathways in their classrooms. And of course we talked to educators about Code Club. It was awesome to hear from club leaders about the work their students accomplished, and many educators were eager to start a new club at their schools! 

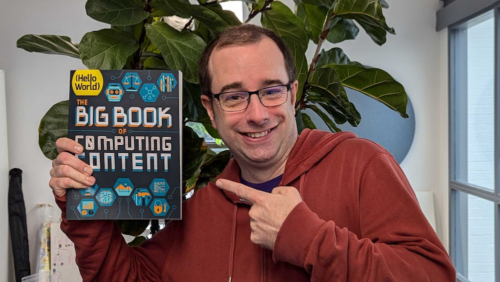
An educator is holding Hello World magazine.
We gave a copy of the second Big Book to all conference attendees.

Back in 2022 at the last in-person CSTA conference, we had donated a copy of our first special edition of Hello World magazine, The Big Book of Computing Pedagogy, for every attendee. This time around, we donated copies of our follow-up special edition, The Big Book of Computing Content. Where the first Big Book focuses on how to teach computing, the second Big Book delves deep into what we teach as the subject of computing, laying it out in 11 content strands.

Our talks about teaching (with) AI

One of the things that makes CSTA conferences so special is the fantastic range of talks, workshops, and other sessions running at and around the conference. We took the opportunity to share some of our work in flash talks and two full-length sessions.

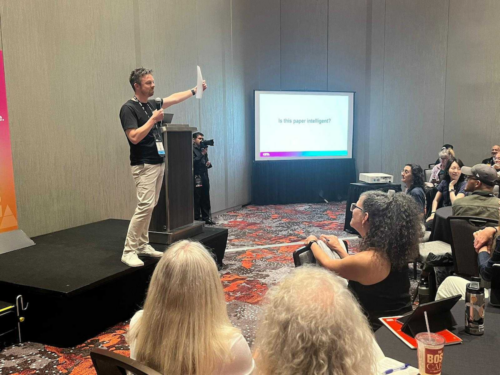
One of the sessions was led by one of our Senior Learning Managers, Ben Garside, who gave a talk to a packed room on what we’ve learned from developing AI education resources for Experience AI. Ben shared insights we’ve gathered over the last two years and talked about the design principles behind the Experience AI resources.

An educator is giving a talk at a conference.
Ben discussed AI education with attendees.

Being in the room for Ben’s talk, I was struck by two key takeaways:

  1. The issue of anthropomorphism, that is, projecting human-like characteristics onto artificial intelligence systems and other machines. This presents several risks and obstacles for young people trying to understand AI technology. In our teaching, we need to take care to avoid anthropomorphizing AI systems, and to help young people shift false conceptions they might bring into the classroom.
  2. Teaching about AI requires fostering a shift in thinking. When we teach traditional programming, we show learners that this is a rules-based, deterministic approach; meanwhile, AI systems based on machine learning are driven by data and statistical patterns. These two approaches and their outcomes are distinct (but often combined), and we need to help learners develop their understanding of the significant differences.

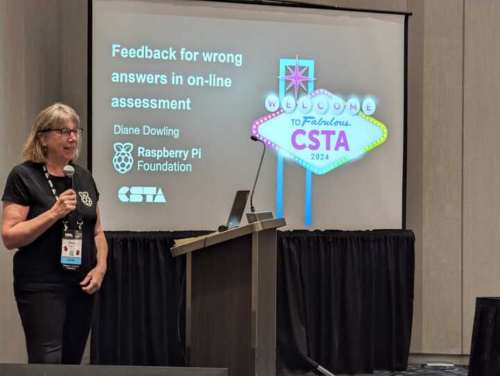
Our second session was led by Diane Dowling, another Senior Learning Manager at the Foundation. She shared some of the development work behind Ada Computer Science, our free platform providing educators and learners with a vast set of questions and content to help understand CS.

An educator is presenting at a conference.
Diane presented our trial with using LLM-based automated feedback.

Recently, we’ve been experimenting with the use of a large language model (LLM) on Ada to provide assessment feedback on long-form questions. This led to a great conversation between Diane and the audience about the practicalities, risks, and implications of such feature.

More on what we learned from CSTA coming soon

We had a fantastic time with the educators in Vegas and are grateful to CSTA and their sponsors for the opportunity to meet and learn from so many different people. We’ll be sharing some of what we learned from the educators we spoke to in a future blog post, so watch this space.

A group of educators standing outside a conference venue.

The post  CSTA 2024: What happened in Las Vegas appeared first on Raspberry Pi Foundation.

AWS Weekly Roundup: Llama 3.1, Mistral Large 2, AWS Step Functions, AWS Certifications update, and more (July 29, 2024)

Post Syndicated from Antje Barth original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-llama-3-1-mistral-large-2-aws-step-functions-aws-certifications-update-and-more-july-29-2024/

I’m always amazed by the talent and passion of our Amazon Web Services (AWS) community members, especially in their efforts to increase diversity, equity, and inclusion in the tech community.

Last week, I had the honor of speaking at the AWS User Group Women Bay Area meetup, led by Natalie. This group is dedicated to empowering and connecting women, providing a supportive environment to explore cloud computing. In Latin America, we recently had the privilege of supporting 12 women-led AWS User Groups from 10 countries in organizing two regional AWSome Women Community Summits, reaching over 800 women builders. There’s still more work to be done, but initiatives like these highlight the power of community in fostering an inclusive and diverse tech environment.

Women-Led AWS Community Events

Now, let’s turn our attention to other exciting news in the AWS universe from last week.

Last week’s launches
Here are some launches that got my attention:

Meta Llama 3.1 models – The Llama 3.1 models are Meta’s most advanced and capable models to date. The Llama 3.1 models are a collection of 8B, 70B, and 405B parameter size models that demonstrate state-of-the-art performance on a wide range of industry benchmarks and offer new capabilities for your generative artificial intelligence (generative AI) applications. Llama 3.1 models are now available in Amazon Bedrock (see Announcing Llama 3.1 405B, 70B, and 8B models from Meta in Amazon Bedrock) and Amazon SageMaker JumpStart (see Llama 3.1 models are now available in Amazon SageMaker JumpStart).

My colleagues Tiffany and Mike explored Llama 3.1 in last week’s episode of the weekly Build On Generative AI live stream. You can watch the full episode here!

BuildOn Generative AI Llama 3.1 launch

Mistral Large 2 model – Mistral Large 2 is the newest version of Mistral Large, and according to Mistral AI, it offers significant improvements across multilingual capabilities, math, reasoning, coding, and much more. Mistral AI’s Mistral Large 2 foundation model (FM) is now available in Amazon Bedrock. See Mistral Large 2 is now available in Amazon Bedrock for all the details. You can find code examples in the Mistral-on-AWS repo and the Amazon Bedrock User Guide.

Faster auto scaling for generative AI models – This new capability in Amazon SageMaker inference can help you reduce the time it takes for your generative AI models to scale automatically. You can now use sub-minute metrics and significantly reduce overall scaling latency for generative AI models. With this enhancement, you can improve the responsiveness of your generative AI applications as demand fluctuates. For more details, check out Amazon SageMaker inference launches faster auto scaling for generative AI models.

AWS Step Functions now supports customer managed keys – AWS Step Functions now supports the use of customer managed keys with AWS Key Management Service (AWS KMS) to encrypt Step Functions state machine and activity resources. This new capability lets you encrypt your workflow definitions and execution data using your own encryption keys. Visit the AWS Step Functions documentation and the AWS KMS documentation to learn more.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS news
Here are some additional news items and posts that you might find interesting:

AWS Certification: Addition of new exam question types – If you are planning to take the AWS Certified AI Practitioner or AWS Certified Machine Learning Engineer – Associate exam anytime soon, check out AWS Certification: Addition of new exam question types. These exams will be the first to include three new question types: ordering, matching, and case study. The post shares insights about the new question types and offers information to help you prepare.

New ordering question type in AWS Certifications

Amazon’s exabyte-scale migration from Apache Spark to Ray on Amazon EC2 – The Business Data Technologies (BDT) team at Amazon Retail has just flipped the switch to start quietly moving management of some of their largest production business intelligence (BI) datasets from Apache Spark over to Ray to help reduce both data processing time and cost. They’ve also contributed a critical component of their work (The Flash Compactor) back to Ray’s open source DeltaCAT project. Find the full story at Amazon’s Exabyte-Scale Migration from Apache Spark to Ray on Amazon EC2.

Running compaction jobs with Ray on Amazon EC2

From community.aws
Here are my top three personal favorites posts from community.aws:

Upcoming AWS events
Check your calendars and sign up for these AWS events:

AWS SummitsAWS Summits – The 2024 AWS Summit season is almost wrapping up! Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Mexico City (August 7), São Paulo (August 15), and Jakarta (September 5).

AWS Community DaysAWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: New Zealand (August 15), Colombia (August 24), New York (August 28), Belfast (September 6), and Bay Area (September 13).

You can browse all upcoming in-person and virtual events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Antje

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

Key Takeaways From The Take Command Summit: Building Resilient Cyber Defenses Through AI

Post Syndicated from Emma Burdett original https://blog.rapid7.com/2024/07/29/key-takeaways-from-the-take-command-summit-building-resilient-cyber-defenses-through-ai/

Key Takeaways From The Take Command Summit: Building Resilient Cyber Defenses Through AI

One of the most talked-about sessions at the Take Command 2024 Cybersecurity Virtual Summit,”Control the Chaos: Building Resilient Cyber Defenses Through AI,” featured experts from AWS and Rapid7 exploring how artificial intelligence is transforming cybersecurity and sharing practical guidance on leveraging AI to enhance cyber defenses.

Here are the key takeaways:

  1. AI Enhances Alert Triage and Contextual Information: Laura Ellis, Vice President of Data Engineering at Rapid7, highlighted the power of AI in managing the overwhelming volume of alerts. “Using AI to help with alert triage… finding that signal, boosting the signal, reducing the noise, and being that assistant to work through that high volume of alerts.” AI can also provide additional context to security teams, helping them make more informed decisions quickly.
  2. The Role of AI in Reducing Manual Tasks: Generative AI can significantly reduce the manual workload on security analysts. Laura said, “we can leverage AI to generate that first report draft for them,” allowing analysts to focus on more critical tasks. This efficiency is crucial in a field where time and precision are paramount.
  3. Collaboration and Governance in AI Integration: Stephen Warwick from AWS emphasized the importance of cross-industry collaboration and robust governance in AI deployment. “AWS collaborates directly with Nvidia… to ensure secure communication between devices and apply responsible AI policies across the board.” This collaboration is vital for developing secure AI solutions that meet industry standards and regulatory requirements.

Our post summit survey revealed that 37% of respondents see the largest potential for Generative AI in detecting advanced threats faster and with more precision. This highlights AI’s role in automating manual tasks and reducing the workload on cybersecurity teams, leading to quicker threat identification and response.

AI offers significant promise in enhancing cyber defenses by improving alert triage, reducing manual tasks, and ensuring robust governance through collaboration. If you’re interested in learning more about how AI can transform your cybersecurity strategy, click through to watch the full session.

Key Takeaways From The Take Command Summit:Command Your Cloud

Post Syndicated from Emma Burdett original https://blog.rapid7.com/2024/07/26/key-takeaways-from-the-take-command-summit-command-your-cloud/

Key Takeaways From The Take Command Summit:Command Your Cloud

The Cloud security landscape is constantly changing. During the “Command Your Cloud” session at the Rapid7 Take Command Summit, industry experts Ryan Blanchard, Jeffrey Gardner and Devin Krugly shared vital strategies for staying ahead of that constant change.

Effective cloud security requires a blend of proactive measures, prioritization based on real-world threats, and strategic automation. In fact, 35% of our post event survey respondents were unsure about the last time their organization experienced a security incident related to their cloud environment. This highlights a potential lack of visibility and communication regarding cloud security incidents within organizations.

Key Takeaways:

  1. Embrace Democratized Access with Caution: The shift to cloud environments has democratized access and authority within organizations, leading to a broader range of individuals who can provision and manage resources. However, this increased access can result in diverse builds and rapid changes, complicating visibility and control. As Jeff Gardner highlighted, “Excess permissions and misconfigurations are natural outcomes of rapid cloud adoption, but they make you an attractive target for attackers.”
  2. Prioritize People and Processes Before Technology: Effective cloud security starts with people and processes. Gardner emphasized the importance of securing buy-in from higher-ups and modeling good security behavior. “Leadership comes from the top.” he said,”…find a champion on the dev team interested in security and build on that.” Additionally, fostering a no-blame culture can encourage teams to learn from mistakes and continuously improve.
  3. Implement Layered Risk Management: Devin Gregory underscored the necessity of a layered risk management approach. This includes understanding business criticality, public accessibility, attack paths, identity-related risks, misconfigurations, and vulnerabilities. He said, “Understanding the data flows and the business requirements helps prioritize what needs to be secured first.”

“One of the things that has really come into focus for security teams is building a collaborative and empathic environment. It’s about including the security and the IT team and the infrastructure team right in the decisions.” – Devin Krugly, Practice Advisor – VRM, Rapid7

Interested in learning more? Watch the full session to dive deeper into these strategies and enhance your cloud security posture.

Introducing quorum queues on Amazon MQ for RabbitMQ

Post Syndicated from Chris Munns original https://aws.amazon.com/blogs/compute/introducing-quorum-queues-on-amazon-mq-for-rabbitmq/

This post is written by Vignesh Selvam (Senior Product Manager – Amazon MQ), Simon Unge (Senior software development engineer – Amazon MQ).

Amazon MQ for RabbitMQ announced support for quorum queues, a type of replicated queue designed for higher availability and data safety. This post presents an overview of this queue type, describes when you should use it, and best practices you can follow. The post also describes how Amazon MQ has also improved quorum queues in the open-source RabbitMQ community.

Overview of quorum queues

A quorum queue is a replicated first in, first out queue type offered by open-source RabbitMQ that uses the Raft consensus algorithm to maintain data consistency. Each quorum queue has a leader and multiple followers (replicas), which ensure that messages are replicated and persisted across a majority of nodes, thus providing resilience against node failures. Quorum queues only need a majority of member nodes (a quorum) to make decisions about data. If a RabbitMQ node hosting a leader becomes unavailable, another node hosting one of the followers is automatically elected as the leader. Once the node becomes available again, the node will become a follower for the quorum queue and catch up or synchronize with the new leader. Quorum queues can detect network failures faster and recover quicker than classic mirrored queues, thus improving the resiliency of the message broker as a whole.

Quorum queues share most of the fundamental features that are key to RabbitMQ replicated queue types such as consumption, consumer acknowledgements, cancelling consumers, purging and deletion. Poison message handling is a unique feature of quorum queues which help developers manage unprocessed messages more efficiently. A poison message is a message that cannot be processed and ends up being repeatedly requeued. Quorum queues keep track of the number of unsuccessful delivery attempts and expose it in the ‘x-delivery-count’ header that is included with any redelivered message. A delivery limit can be set using a policy argument for ’delivery-limit’. If the limit is reached, the message can be dropped or put in a dead-letter queue. This feature further improves the data reliability of a quorum queue.

You can get started with quorum queues by explicitly specifying the ‘x-queue-type’ parameter as ’quorum’ on a RabbitMQ broker running version 3.13 and above. We recommend that you change the default vhost queue type to ’quorum’ to ensure that all queues are created as quorum queues by default inside a vhost.

RabbitMQ queues console

RabbitMQ queues console

When should you use quorum queues?

You should use quorum queues when you need higher availability and consistency for their messaging infrastructure. Quorum queues are ideal for scenarios where data durability and fault tolerance are critical, such as financial transaction systems, e-commerce data processing systems, or any application requiring high reliability. They are particularly beneficial in environments where node failures are more likely or where maintaining data consistency across distributed systems is essential.

When should you NOT use quorum queues?

Quorum queues are not meant to be temporary. They do not support transient or exclusive queues and are not meant to be used in scenarios with high queue churn (declaration and deletion rates). They are also not recommended for unreplicated queues.

Best practices for quorum queues

Quorum queues perform better when the queues are short. You can set the maximum queue length using a policy or queue arguments to limit the total memory usage by queues (max-length, max-length-bytes).

Add a new queue dialog

Add a new queue dialog

Amazon MQ recommends publishers to use publisher confirms and consumers to use manual acknowledgements on quorum queues. Publisher confirms will only be issued once a published message has been successfully replicated to a quorum of nodes and is considered safe within the context of the system. Publisher confirms can also serve as a form of back pressure and protect the availability of the broker during periods of high workload. Manual acknowledgements are used to ensure messages that are not processed can be returned to the queue for reprocessing.

Open-source improvements by Amazon MQ

Amazon MQ contributed multiple improvements to the open-source RabbitMQ community to improve quorum queues for operators and users.

Automatic membership reconciliation
Quorum queues depend on a majority of replicas being available for the Raft consensus algorithm. Amazon MQ identified that many users and operators would prefer to maintain a certain minimal number of replicas (generally 3 or 5) at all times to ensure a majority always exists. The quorum queue replica management was also initially available only via CLI tools. Amazon MQ engineers introduced automatic membership reconciliation to improve this experience. Now, RabbitMQ can be configured to identify any queues that are below a target group member size, and automatically grow or add a node to the queue members. Thus ensuring a certain minimum number of replicas always exist.

Voter status
RabbitMQ considers a quorum queue member node to be a full member even if the member has not caught up or fully synced to the quorum. The CLI command rabbitmq-queues check_if_node_is_ quorum_critical can provide a false positive, and indicate a node is safe to remove, even though another node has queue members that are still synchronizing to the quorum. Amazon MQ introduced a new ‘non-voter’ state for a queue member node to indicate a member that is still catching up or synchronizing to the quorum. If a queue has a member in this state, it is not considered a full member. Once the member is fully synchronized, it is automatically promoted to the voter status, and is considered a full member. The command rabbitmq-queues check_if_node_is_quorum_critical now takes this into account and correctly reports if a node can be safely terminated without any queues becoming unavailable due to a loss of majority.

Inconsistent state management
When a broker is overloaded, a quorum queue can end up in an inconsistent state, where the quorum queue membership state stored in the Raft state machine differs from the RabbitMQ internal state for the queue. Amazon MQ introduced a periodic check per quorum queue that identifies if a queue has an inconsistent state and takes action to fix it.

Default queue type
The default queue type for a RabbitMQ broker vhost was classic queues. You could declare a different queue type by explicitly stating the ’x-queue-type’ as a queue creation argument. Amazon MQ introduced a global default queue type in the configuration file (rabbit.conf) that provides the ability to define a default queue type at the broker level. Now, an operator can change the default queue type to quorum queues if not specified during creation.

Membership management permissions
RabbitMQ users are able to configure the quorum queue membership using the management API. This can interfere with automatic membership reconciliation. Amazon MQ introduced the ability for an operator to turn off the membership management permissions available through the management API. Thus, preventing customers from accidentally affecting their broker.

Conclusion

Quorum queues on RabbitMQ provide a robust solution for scenarios requiring high availability and resilience. By leveraging the Raft consensus protocol, quorum queues ensure that messages are safely stored and replicated across a quorum of nodes, making them an excellent choice for modern, distributed message queuing systems.

Amazon MQ recommends that you adopt quorum queues as the preferred replicated queue type on RabbitMQ 3.13 brokers. For more details, see Amazon MQ documentation. To know more about the open-source feature, see quorum queues.

Get started with quorum queues on Amazon MQ for RabbitMQ 3.13 with a few clicks.

Unveiling Key Insights from the 2024 Take Command Summit

Post Syndicated from Emma Burdett original https://blog.rapid7.com/2024/07/18/unveiling-key-insights-from-the-2024-take-command-summit/

Unveiling Key Insights from the 2024 Take Command Summit

The 2024 Take Command Summit, held virtually in partnership with AWS, united over 2,000 security professionals to delve into critical cybersecurity issues. Our infographic captures the essence of the summit, showcasing expert insights from 10 sessions on topics like new attack intelligence, AI disruptions, and transparent MDR partnerships.

We also highlight attendees’ thoughts on various subject matters, from AI’s role in security to the importance of collaboration and communication. Check out the key highlights, stand out stats, and engaging stories can inform your security strategies and keep your organization ahead of emerging threats.

Unveiling Key Insights from the 2024 Take Command Summit

Takeaways From The Take Command Summit: Unlocking ROI in Security

Post Syndicated from Emma Burdett original https://blog.rapid7.com/2024/07/10/takeaways-from-the-take-command-summit-unlocking-roi-in-security/

Takeaways From The Take Command Summit: Unlocking ROI in Security

Rapid7 CMO Cindy Stanton hosted a discussions with Cindy Stanton, Byron Anderson, Principal InfoSec Engineer, KinderCare Learning Companies and Gaël Frouin Director IT Security, AAA Northeast to talk strategies for measuring team performance and demonstrating ROI in cybersecurity at Rapid7’s recent Take Command summit. The panelists highlighted the importance of clear objectives, noting many security projects fail due to poorly defined goals.

Our post summit survey of attendees showed that 56% of respondents identified limited resources as the biggest inhibitor to measuring security program success. Overcoming these challenges with clear goals, regular metrics, and automation can significantly enhance cybersecurity efforts.

Key Takeaways:

  1. Regular Communication and Metrics: Organizations prioritizing regular communication and metrics-driven approaches are much more likely to achieve positive outcomes.
  2. Risk Metrics as a Common Language: Byron Anderson emphasized using risk metrics to facilitate conversations about decommissioning outdated systems, reducing risk, and ensuring accountability.
  3. Automation and Integration: Gaël Frouin stressed the necessity of automation for efficiency and achieving the best ROI, urging security professionals to consider automation in every process.

“Giving impacted teams a voice early on, and getting them involved, and giving them a sense of ownership, really helped with the success of the projects.” – Byron Anderson, Principal InfoSec Engineer, KinderCare Learning Companies

To dive deeper into these insights and actionable tactics, watch the full video of the session.

Takeaways From The Take Command Summit: Navigating Modern SOC Challenges

Post Syndicated from Emma Burdett original https://blog.rapid7.com/2024/07/02/takeaways-from-the-take-command-summit-navigating-modern-soc-challenges/

Takeaways From The Take Command Summit: Navigating Modern SOC Challenges

At our recent Take Command summit, experts delved into the pressing challenges faced by SOC teams. With 2,365 more data breaches in 2023 than in 2022 (74% of which were a direct result of cyber attacks), the need for robust security operations has never been greater.

Key takeaways from the 25 minute panel:

  1. Emphasizing Proactive Defense: SOC teams must prioritize proactive threat detection and intelligence gathering to stay ahead of evolving cyber threats.
  2. Enhancing Response Times: Reducing incident response times is crucial for mitigating the impact of security breaches and minimizing damage.
  3. Leveraging Advanced Tools: Utilizing advanced threat detection technologies, such as AI and machine learning, can significantly improve the ability to identify and respond to sophisticated attacks.

Key Quote:

“The increasing use of native tools by threat actors means they can stay hidden longer, complicating our detection efforts.”  – Lonnie Best, Detection & Response Services Manager, Rapid7.

The evolving threat landscape requires SOC teams to enhance detection capabilities and streamline operations. To dive deeper into these insights, click through to watch the full discussion.

Takeaways From The Take Command Summit: Unprecedented Threat Landscape

Post Syndicated from Emma Burdett original https://blog.rapid7.com/2024/06/26/takeaways-from-the-take-command-summit-unprecedented-threat-landscape/

Takeaways From The Take Command Summit: Unprecedented Threat Landscape

The Rapid7 Take Command summit unveiled crucial findings from the 2024 Attack Intelligence Report, offering invaluable insights for cybersecurity professionals navigating today’s complex threat landscape.

Key takeaways from the 30 minute panel:

  1. Rise of Zero-Day Exploits: 53% of mass compromise events in 2023 and early 2024 began with zero-day exploits. This highlights the urgent need for improved patch management and proactive defense strategies.
  2. Network Edge Vulnerabilities: Over a third of the vulnerabilities leading to mass compromise events were in network edge technologies, such as firewalls and VPNs, emphasizing the importance of securing these critical points.
  3. Ransomware on the Rise: Rapid7 tracked over 5,600 ransomware incidents in 2023 and early 2024, with ransomware payouts exceeding $1 billion. The sheer volume underscores the importance of robust defenses and incident response plans.

Key Quote:

“Our research shows that more than 40% of incident responses in 2023 stemmed from remote remote access exploits without multifactor authentication. Basic security components are still crucial in making attacks harder.” – Caitlin Condon, Director Vulnerability Intelligence, Rapid7

The 2024 Attack Intelligence Report provides deep insights into the evolving threat landscape, highlighting the rise of zero-day exploits, the critical vulnerabilities in network edge technologies, and the rampant increase in ransomware incidents, you can view it here.

For a deeper dive into these findings, click through to watch the full video and stay ahead of attackers.

Takeaways From The Take Command Summit: Understanding Modern Cyber Attacks

Post Syndicated from Emma Burdett original https://blog.rapid7.com/2024/06/25/takeaways-from-the-take-command-summit-understanding-modern-cyber-attacks/

Takeaways From The Take Command Summit: Understanding Modern Cyber Attacks

In today’s cybersecurity landscape, staying ahead of evolving threats is crucial. The State of Security Panel from our Take Command summit held May 21st delved into how artificial intelligence (AI) is reshaping cyber attacks and defenses.

The discussion highlighted the dual role of AI in cybersecurity, presenting both challenges and solutions. To learn more about these insights and protect your organization from sophisticated threats, watch the full video.

Key takeaways from the 30 minute panel:

  1. AI-Enhanced Attacks: Friendly Hacker and CEO of SocialProof Security Rachel Tobac highlighted the growing use of AI by attackers, stating, “Eight times out of ten, I’m using AI tools during my attacks.” AI helps create convincing phishing emails and scripts, making attacks more efficient and scalable.
  2. Voice Cloning and Deepfakes: Attackers are now using AI for voice cloning and deep fakes, making it vital for organizations to verify identities through multiple communication channels. Rachel continued, “We can even do a deep fake, live during a Teams or Zoom call to trick somebody.”
  3. Cloud Vulnerabilities: Rapid7’s Chief Security Officer Jaya Baloo pointed out that roughly  45% of data breaches are due to cloud issues, caused by misconfigurations and vulnerabilities, making cloud security a critical focus.

“Professional paranoia is something that I think we should hold dear to us,” Jaya Bayloo, Chief Security Officer, Rapid7

Watch the full video here.

Takeaways From The Take Command Summit: Understanding Modern Cyber Attacks

Post Syndicated from Emma Burdett original https://blog.rapid7.com/2024/06/21/takeaways-from-the-take-command-summit-understanding-modern-cyber-attacks/

Takeaways From The Take Command Summit: Understanding Modern Cyber Attacks

In today’s cybersecurity landscape, staying ahead of evolving threats is crucial. The State of Security Panel from our Take Command summit held May 21st delved into how artificial intelligence (AI) is reshaping cyber attacks and defenses.

The discussion highlighted the dual role of AI in cybersecurity, presenting both challenges and solutions. To learn more about these insights and protect your organization from sophisticated threats, watch the full video.

Key takeaways from the 30 minute panel:

  1. AI-Enhanced Attacks: Friendly Hacker and CEO of SocialProof Security Rachel Tobac highlighted the growing use of AI by attackers, stating, “Eight times out of ten, I’m using AI tools during my attacks.” AI helps create convincing phishing emails and scripts, making attacks more efficient and scalable.
  2. Voice Cloning and Deepfakes: Attackers are now using AI for voice cloning and deep fakes, making it vital for organizations to verify identities through multiple communication channels. Rachel continued, “We can even do a deep fake, live during a Teams or Zoom call to trick somebody.”
  3. Cloud Vulnerabilities: Rapid7’s Chief Security Officer Jaya Baloo pointed out that roughly  45% of data breaches are due to cloud issues, caused by misconfigurations and vulnerabilities, making cloud security a critical focus.

“Professional paranoia is something that I think we should hold dear to us,” – Jaya Bayloo, Chief Security Officer, Rapid7

Watch the full video here.

Application Security at re:Inforce 2024

Post Syndicated from Daniel Begimher original https://aws.amazon.com/blogs/security/application-security-at-reinforce-2024/

Join us in Philadelphia, Pennsylvania, on June 10–12, 2024, for AWS re:Inforce, a security learning conference where you can enhance your skills and confidence in cloud security, compliance, identity, and privacy. As an attendee, you will have access to hundreds of technical and non-technical sessions, an Expo featuring Amazon Web Services (AWS) experts and AWS Security Competency Partners, and keynote sessions led by industry leaders. AWS re:Inforce offers a comprehensive focus on six key areas, including Application Security.

The Application Security track helps you understand and implement best practices for securing your applications throughout the development lifecycle. This year, we are focusing on several key themes:

  • Building a culture of security – Learn how to define and influence organizational behavior to speed up application development, while reducing overall security risk through implementing best practices, training your internal teams, and defining ownership.
  • Security of the pipeline – Discover how to embed governance and guardrails to allow developer agility, while maintaining security across your continuous integration and delivery (CI/CD) pipelines.
  • Security in the pipeline – Explore tooling and automation to reduce the mean time of security reviews and embed continuous security into each stage of the development pipeline.
  • Supply chain security – Gain improved awareness of how risks are introduced by extension, track dependencies, and identify vulnerabilities used in your software.

Additionally, this year the Application Security track will have sessions focused on generative AI (gen AI), covering how to secure gen AI applications and use gen AI for development. Join these sessions to deepen your knowledge and up-level your skills, so that you can build modern applications that are robust, resilient, and secure.

Breakout sessions, chalk talks, lightning talks, and code talks

APS201 | Breakout session | Accelerate securely: The Generative AI Security Scoping Matrix
As generative AI ignites business innovation, cybersecurity teams need to keep up with the accelerating domain. Security leaders are seeking tools and answers to help drive requirements around governance, compliance, legal, privacy, threat mitigations, resiliency, and more. This session introduces you to the Generative AI Security Scoping Matrix, which is designed to provide a common language and thought model for approaching generative AI security. Leave the session with a framework, techniques, and best practices that you can use to support responsible adoption of generative AI solutions designed to help your business move at an ever-increasing pace.

APS301 | Breakout session | Enhance AppSec: Generative AI integration in AWS testing
This session presents an in-depth look at the AWS Security Testing program, emphasizing its scaling efforts to help ensure new products and services meet a high security bar pre-launch. With a focus on integrating generative AI into its testing framework, the program showcases how AWS anticipates and mitigates complex security threats to maintain cloud security. Learn about AWS’s proactive approaches to collaboration across teams and mitigating vulnerabilities, enriched by case studies that highlight the program’s flexibility and dedication to security excellence. Ideal for security experts and cloud architects, this session offers valuable insights into safeguarding cloud computing technologies.

APS302 | Breakout session | Building a secure MLOps pipeline, featuring PathAI
DevOps and MLOps are both software development strategies that focus on collaboration between developers, operations, and data science teams. In this session, learn how to build modern, secure MLOps using AWS services and tools for infrastructure and network isolation, data protection, authentication and authorization, detective controls, and compliance. Discover how AWS customer PathAI, a leading digital pathology and AI company, uses seamless DevOps and MLOps strategies to run their AISight intelligent image management system and embedded AI products to support anatomic pathology labs and bio-pharma partners globally.

APS401 | Breakout session | Keeping your code secure
Join this session to dive deep into how AWS implemented generative AI tooling in our developer workflows. Learn about the AWS approach to creating the underlying code scanning and remediation engines that AWS uses internally. Also, explore how AWS integrated these tools into the services we offer through reactive and proactive security features. Leave this session with a better understanding of how you can use AWS to secure code and how the code offered to you through AWS generative AI services is designed to be secure.

APS402 | Breakout session | Verifying code using automated reasoning
In this session, AWS principal applied scientists discuss how they use automated reasoning to certify bug-free code mathematically and help secure underlying infrastructure. Explore how to use Kani, an AWS created open source engine that analyzes, verifies, and detects errors in safe and unsafe Rust code. Hear how AWS built and implemented Kani internally with examples taken from real-world AWS open source code. Leave this session with the tools you need to get started using this Rust verification engine for your own workloads.

APS232 | Chalk talk | Successful security team patterns
It’s more common to hear what a security team does than to hear how the security team does it, or with whom the security team works rather than how it was designed to work. Organizational design is often demoted to a secondary consideration behind the goals of a security team, despite intentional design generally being what empowers, or hinders, security teams from achieving their goals. Security must work across the organization, not in isolation. This chalk talk focuses on designing effective security teams for organizations moving to the cloud, which necessitates outlining both what the security team works on and how it achieves that work.

APS331 | Chalk talk | Verifiable and auditable security inside the pipeline
In this chalk talk, explore platform engineering best practices at AWS. AWS deploys more than 150 million times per year while maintaining 143 different compliance framework attestations and certifications. Internally, AWS has learned how to make security easier for builder teams. Learn key risks associated with operating pipelines at scale and Amazonian mechanisms to make security controls inside the pipeline verifiable and auditable so that you can shift compliance and auditing left into the pipeline.

APS233 | Chalk talk | Threat modeling your generative AI workload to evaluate security risk
As the capabilities and possibilities of machine learning continue to expand with advances in generative AI, understanding the security risks introduced by these advances is essential for protecting your valuable AWS workloads. This chalk talk guides you through a practical threat modeling approach, empowering you to create a threat model for your own generative AI applications. Gain confidence to build your next generative AI workload securely on AWS with the help of threat modeling and leave with actionable steps you can take to get started.

APS321 | Lightning talk | Using generative AI to create more secure applications
Generative AI revolutionizes application development by enhancing security and efficiency. This lightning talk explores how Amazon Q, your generative AI assistant, empowers you to build, troubleshoot, and transform applications securely. Discover how its capabilities streamline the process, allowing you to focus on innovation while ensuring robust security measures. Unlock the power of generative AI for helping build secure, cutting-edge applications.

APS341 | Code talk | Shifting left, securing right: Container supply chain security
Supply chain security for containers helps ensure you can detect software security risks in third-party packages and remediate them during the container image build process. This prevents container images with vulnerabilities from being pushed to your container registry and causing potential harm to your production systems. In this code talk, learn how you can apply a shift-left approach to container image security testing in your deployment pipelines.

Hands-on sessions

APS373 | Workshop | Build a more secure generative AI chatbot with security guardrails
Generative AI is an emerging technology that is disrupting multiple industries. An early generative AI use case is interactive chat in customer service applications. As users interact with generative AI chatbots, there are security risks, such as prompt injection and jailbreaking resulting from specially crafted inputs sent to large language models. In this workshop, learn how to build an AI chatbot using Amazon Bedrock and protect it using Guardrails for Amazon Bedrock. You must bring your laptop to participate.

APS351 | Builders’ session | Implement controls for the OWASP Top 10 for LLM applications
In this builders’ session, learn how to implement security controls that address the OWASP Top 10 for LLM applications on AWS. Experts guide you through the use of AWS security tooling to provide practical insights and solutions to mitigate the most critical security risks outlined by OWASP. Discover technical options and choices you can make in cloud infrastructure and large-scale enterprise environments augmented by AWS generative AI technology. You must bring your laptop to participate.

APS271 | Workshop | Threat modeling for builders
In this workshop, learn threat modeling core concepts and how to apply them through a series of group exercises. Key topics include threat modeling personas, key phases, data flow diagrams, STRIDE, and risk response strategies as well as the introduction of a “threat grammar rule” with an associated tool. In exercises, identify threats and mitigations through the lens of each threat modeling persona. Assemble in groups and walk through a case study, with AWS threat modeling experts on hand to guide you and provide feedback. You must bring your laptop to participate.

APS371 | Workshop | Integrating open source security tools with AWS code services
AWS, open source, and partner tooling work together to accelerate your software development lifecycle. In this workshop, learn how to use the Automated Security Helper (ASH), an open source application security tool, to quickly integrate various security testing tools into your software build and deployment flows. AWS experts guide you through the process of security testing locally on your machines and within the AWS CodeCommit, AWS CodeBuild, and AWS CodePipeline services. In addition, discover how to identify potential security issues in your applications through static analysis, software composition analysis, and infrastructure-as-code testing. You must bring your laptop to participate.

This blog post highlighted some of the unique sessions in the Application Security track at the upcoming re:Inforce 2024 conference in Philadelphia. If these sessions pique your interest, register for re:Inforce 2024 to attend them, along with the numerous other Application Security sessions offered at the conference. For a comprehensive overview of sessions across all tracks, explore the AWS re:Inforce catalog preview.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Daniel Begimher

Daniel Begimher
Daniel is a Senior Security Engineer specializing in cloud security and incident response solutions. He holds all AWS certifications and authored the open-source code scanning tool, Automated Security Helper. In his free time, Daniel enjoys gadgets, video games, and traveling.

Ipolitas Dunaravich

Ipolitas Dunaravich
Ipolitas is a technical marketing leader for networking and security services at AWS. With over 15 years of marketing experience and more than 4 years at AWS, Ipolitas is the Head of Marketing for AppSec services and curates the security content for re:Inforce and re:Invent.