Today, I’m happy to announce AWS Shield network security director (preview), a capability that simplifies identification of configuration issues related to threats such as SQL injections and distributed denial of service (DDoS) events, and proposes remediations. This feature identifies and analyzes network resources, connections, and configurations. It compares them against AWS best practices to create a network topology that highlights resources requiring protection.
Organizations today face significant challenges in maintaining a robust network security posture. Security teams often struggle to efficiently discover all resources in their environments, understand how these resources are interconnected, and identify which security services are currently configured. Additionally, they find determining how well resources are configured relative to AWS best practices requires considerable expertise and effort. Many teams find it difficult to identify which network security services and rule sets would best protect their applications from common and emerging threats.
AWS Shield network security director addresses these challenges through three key capabilities. First, it performs comprehensive analysis to discover resources across your AWS accounts, identify connectivity between resources, and determine which network security services and configurations are currently in place. Second, it prioritizes resources by severity level based on AWS network security best practices and threat intelligence. Finally, it provides specific remediation recommendations such as step-by-step instructions for implementing the right AWS security services, including AWS WAF, Amazon Virtual Private Cloud (Amazon VPC)security groups, and Amazon VPC network access control lists (ACLs) to protect your resources.
The service supports critical network security use cases, including protecting applications against internet-born threats and controlling human access to resources based on port, protocol, or IP address range. It provides network analysis to discover assets and delivers analysis that eliminates time-consuming manual processes for identifying resources that need protection. The service offers resource prioritization by assigning security findings a severity level based on network context and adherence to AWS best practices, helping you focus on what matters most. Additionally, it supplies actionable recommendations with specific guidance on which services and configurations will address each security gap. You can also get answers, in natural language, from AWS Shield network security director from within Amazon Q Developer in the AWS Management Console and chat applications.
Getting started with AWS Shield network security director To use AWS Shield network security director, I need to initiate a network analysis of my AWS resources. I go to the AWS WAF & Shield console and choose Getting started under AWS Shield network security director in the navigation pane. I choose Get started, which takes me to the configuration page. On this page, I can choose how to perform my first network analysis: I can assess findings from across all supported Regions or from my current Region only. I select Start network analysis.
After the analysis is completed, the dashboard page shows a breakdown of resource types by severity level and the most common categories of network security findings associated with their resources. Resources are categorized by type and severity level (critical, high, medium, low, informational), making it easy to identify which areas need immediate attention.
Next, I explore the Resources section to understand the distribution of my assets and filter by severity level in my environment. I can use Resource overview to review a specific severity level, which will redirect me to the Resources under Network security director with the associated severity level filter. I choose the resources that have Medium severity level.
I choose a specific resource to view its network topology map showing how it connects to other resources and associated findings. This visualization helps me understand the potential impact of security configurations and identify exposed paths. I review detailed findings such as “Allows unrestricted inbound access (0.0.0.0/0) on all ports” with severity ratings.
Next, I go to Findings under Network security director, which shows common configuration issues. For each finding, I receive detailed information and recommended remediation steps. The service rates the severity of findings (high, medium, low) to help me prioritize my response. Critical-severity findings such as “CloudFront origin is also internet accessible without CloudFront protections” or high-severity findings such as “Allows unrestricted inbound access (0.0.0.0/0) on all ports” are presented first, followed by medium- and low-severity issues.
You can analyze your network security configurations, in natural language, with AWS Shield network security director within Amazon Q Developer in the AWS Management Console and chat applications. For example, you can say “Do I have any network security issues on my CloudFront distributions?” or “Are any of my resources vulnerable to bots and scrapers?” This integration helps security teams quickly understand their security posture and receive guidance on implementing best practices without having to navigate through extensive documentation.
To explore this capability, I ask “What are my most critical network security issues?” in the Explore with Amazon Q section. Amazon Q analyzes my network security configuration and generates a response based on the security assessment of my AWS environment.
With this comprehensive view of your network security, you can now make data-driven decisions to strengthen your defenses against emerging threats.
Join the preview AWS Shield network security director is available in the US East (N. Virginia) and Europe (Stockholm) Regions. The Amazon Q Developer capability to analyze network security configurations is available in preview in US East (N. Virginia). To begin strengthening your network security, visit the AWS Shield network security director console and initiate your first network security analysis.
Today, we’re announcing a new simplified onboarding experience for Amazon CloudFront that developers can use to accelerate and secure their web applications in seconds. This new experience, along with improvements to the AWS WAF console experience, makes it easier than ever for developers to configure content delivery and security services without requiring deep technical expertise.
Setting up content delivery and security for web applications traditionally required navigating multiple Amazon Web Services (AWS) services and making numerous configuration decisions. With this new CloudFront onboarding experience, developers can now create a fully configured distribution with DNS and a TLS certificate in just a few clicks.
Amazon CloudFront offers compelling benefits for organizations of all sizes looking to deliver content and applications globally. As a content delivery network (CDN), CloudFront significantly improves application performance by serving content from edge locations closest to your users, reducing latency and improving user experience. Beyond performance, CloudFront provides built-in security features that protect your applications from distributed denial of service (DDoS) attacks and other threats at the edge, preventing malicious traffic from reaching your origin infrastructure. The service automatically scales with your traffic demands without requiring any manual intervention, handling both planned and unexpected traffic spikes with ease. Whether you’re running a small website or a large-scale application, the CloudFront integration with other AWS services and the new simplified console experience makes it easier than ever to implement these essential capabilities for your web applications.
Streamlined CloudFront configuration
The new CloudFront console experience guides developers through a simplified workflow that starts with the domain name they want to use for their distribution. When using Amazon Route 53, the experience automatically handles TLS certificate provisioning and DNS record configuration, while incorporating security best practices by default. This unified approach eliminates the need to switch between multiple services like AWS Certificate Manager, Route 53, and AWS WAF, and offers developers a faster time to production without the need to dive deep on the nuanced configuration options of each service.
For example, a developer can now create a secure CloudFront distribution for their applications fronted by a load balancer by entering their domain name and selecting their load balancer as the origin. The console automatically recommends optimal CDN and security configurations based on the application type and requirements, and developers can deploy with confidence knowing they’re following AWS best practices.
For developers who wish to host a static website on Amazon Simple Storage Service (Amazon S3), CloudFront provides several important benefits. First, it improves your website’s performance by caching content at edge locations closer to your users, reducing latency and improving page load times. Second, it helps protect your S3 bucket by acting as a security layer—CloudFront can be configured to be the only way to access your content, preventing direct access to your S3 bucket. The new experience automatically configures these security best practices for you.
Enhanced security integration with AWS WAF
Complementing the new CloudFront experience, we’re also introducing an improved AWS WAF console that features intelligent Rule Packs—curated sets of security rules based on application type and security requirements. These Rule Packs enable developers to implement comprehensive security controls without needing to be security experts.
When creating a CloudFront distribution, developers can now enable AWS WAF protection through an integrated experience that uses these new Rule Packs. The console provides clear recommendations for security configurations that developers can use to preview and validate their settings before deployment.
Web applications face numerous security threats today, including SQL injection attacks, cross-site scripting (XSS), and other OWASP Top 10 vulnerabilities. With the new AWS WAF integration, you automatically get protection against these common attack vectors. The recommended Rule Packs provide immediate protection against malicious bot traffic, common web exploits, and known bad actors while preventing direct-to-origin attacks that could overwhelm your infrastructure.
Let’s take a look
If you’ve ever created an Amazon CloudFront distribution, you’ll immediately notice that things have changed. The new experience is straightforward to follow and understand. For my example, I chose to create a distribution for a static website using Amazon S3 as my origin.
In Step 1, I give my distribution a name and select from Single website or app or the new Multi-tenant architecture option, which I can use to configure distributions that use multiple domains but share a common configuration. I choose Single website or app and enter an optional domain name. With the new experience, I can use the Check domain button to verify I have my domain as a Route 53 zone file.
Next, I select the origin for the distribution, which is where CloudFront will fetch the content to serve and cache. For my Origin type, I select Amazon S3. As the preceding screenshot shows, there are several additional options to choose from. Each of the options is designed to make configuration as straightforward as possible for the most popular use cases. Next, I select my S3 bucket, either by typing in the bucket name or using the Browse S3 button.
Next, I have several settings related to using Amazon S3 as my origin. The Grant CloudFront access to origin option is an important one. This option (selected by default) will update my S3 bucket policy to allow CloudFront to access my bucket and will configure my bucket for origin access control. This way, I can use a completely private bucket and know that assets in my bucket can only be accessed through CloudFront. This is a critical step to keeping my bucket and assets secure.
In the next step, I’m presented with the option to configure AWS WAF. With AWS WAF enabled, my web servers are better protected because it inspects each incoming request for potential threats before allowing them to make their way to my web servers. There is a cost to enabling AWS WAF, and as you can see in the following screenshot, there is a calculator to help estimate additional charges.
Now available
The new CloudFront onboarding experience and enhanced AWS WAF console are available today in all AWS Regions where these services are offered. You can start using these new features through the AWS Management Console. There are no additional charges for using these new experiences—you pay only for the CloudFront and AWS WAF resources you use, based on their respective pricing models.
To learn more about the new CloudFront onboarding experience and AWS WAF improvements, visit the Amazon CloudFront Documentation and AWS WAF Documentation. Start building faster, more secure web applications today with these simplified experiences.
Now you can export public certificates from ACM, get access to the private keys, and use them on any workloads running on Amazon Elastic Compute Cloud (Amazon EC2) instances, containers, or on-premises hosts. The exportable public certificate are valid for 395 days. There is a charge at time of issuance, and again at time of renewal. Public certificates exported from ACM are issued by Amazon Trust Services and are widely trusted by commonly used platforms such as Apple and Microsoft and popular web browsers such as Google Chrome and Mozilla Firefox.
ACM exportable public certificates in action To export a public certificate, you first request a new exportable public certificate. You cannot export previously created public certificates.
To get started, choose Request certificate in the ACM console and choose Enable export in the Allow export section. If you select Disable export, the private key for this certificate will be disallowed for exporting from ACM and this cannot be changed after certificate issuance.
You can also use the request-certificate command to request a public exportable certificate with Export=ENABLED option on the AWS Command Line Interface (AWS CLI).
After you request the public certificate, you must validate your domain name to prove that you own or control the domain for which you are requesting the certificate. The certificate is typically issued within seconds after successful domain validation.
When the certificate enters status Issued, you can export your issued public certificate by choosing Export.
Enter a passphrase for encrypting the private key. You will need the passphrase later to decrypt the private key. To get the public key, Choose Generate PEM Encoding.
You can copy the PEM encoded certificate, certificate chain, and private key or download each to a separate file.
You can use the export-certificate command to export a public certificate and private key. For added security, use a file editor to store your passphrase and output keys to a file to prevent being stored in the command history.
You can now use the exported public certificates for any workload that requires SSL/TLS communication such as Amazon EC2 instances. To learn more, visit Configure SSL/TLS on Amazon Linux in your EC2 instances.
Things to know Here are a couple of things to know about exportable public certificates:
Key security – An administrator of your organization can set AWS IAM policies to authorize roles and users who can request exportable public certificates. ACM users who have current rights to issue a certificate will automatically get rights to issue an exportable certificate. ACM admins can also manage the certificates and take actions such as revoking or deleting the certificates. You should protect exported private keys using secure storage and access controls.
Revocation – You may need to revoke exportable public certificates to comply with your organization’s policies or mitigate key compromise. You can only revoke the certificates that were previously exported. The certificate revocation process is global and permanent. Once revoked, you can’t retrieve revoked certificates to reuse. To learn more, visit Revoke a public certificate in the AWS documentation.
Renewal – You can configure automatic renewal events for exportable public certificates by Amazon EventBridge to monitor certificate renewals and create automation to handle certificate deployment when renewals occur. To learn more, visit Using Amazon EventBridge in the AWS documentation. You can also renew these certificates on-demand. When you renew the certificates, you’re charged for a new certificate issuance. To learn more, visit Force certificate renewal in the AWS documentation.
Now available You can now issue exportable public certificates from ACM and export the certificate with the private keys to use other compute workloads as well as ELB, Amazon CloudFront, and Amazon API Gateway.
You are subject to additional charges for an exportable public certificate when you create it with ACM. It costs $15 per fully qualified domain name and $149 per wildcard domain name. You only pay once during the lifetime of the certificate and will be charged again only when the certificate renews. To learn more, visit the AWS Certificate Manager Service Pricing page.
Today, we’re announcing a new capability in AWS IAM Access Analyzer that helps security teams verify which AWS Identity and Access Management (IAM) roles and users have access to their critical AWS resources. This new feature provides comprehensive visibility into access granted from within your Amazon Web Services (AWS) organization, complementing the existing external access analysis.
Security teams in regulated industries, such as financial services and healthcare, need to verify access to sensitive data stores like Amazon Simple Storage Service (Amazon S3) buckets containing credit card information or healthcare records. Previously, teams had to invest considerable time and resources conducting manual reviews of AWS Identity and Access Management (IAM) policies or rely on pattern-matching tools to understand internal access patterns.
The new IAM Access Analyzer internal access findings identify who within your AWS organization has access to your critical AWS resources. It uses automated reasoning to collectively evaluate multiple policies, including service control policies (SCPs), resource control policies (RCPs), and identity-based policies, and generates findings when a user or role has access to your S3 buckets, Amazon DynamoDB tables, or Amazon Relational Database Service (Amazon RDS) snapshots. The findings are aggregated in a unified dashboard, simplifying access review and management. You can use Amazon EventBridge to automatically notify development teams of new findings to remove unintended access. Internal access findings provide security teams with the visibility to strengthen access controls on their critical resources and help compliance teams demonstrate access control audit requirements.
Let’s try it out
To begin using this new capability, you can enable IAM Access Analyzer to monitor specific resources using the AWS Management Console. Navigate to IAM and select Analyzer settings under the Access reports section of the left-hand navigation menu. From here, select Create analyzer.
From the Create analyzer page, select the option of Resource analysis – Internal access. Under Analyzer details, you can customize your analyzer’s name to whatever you prefer or use the automatically generated name. Next, you need to select your Zone of trust. If your account is the management account for an AWS organization, you can choose to monitor resources across all accounts within your organization or the current account you’re logged in to. If your account is a member account of an AWS organization or a standalone account, then you can monitor resources within your account.
The zone of trust also determines which IAM roles and users are considered in scope for analysis. An organization zone of trust analyzer evaluates all IAM roles and users in the organization for potential access to a resource, whereas an account zone of trust only evaluates the IAM roles and users in that account.
For this first example, we assume our account is the management account and create an analyzer with the organization as the zone of trust.
Next, we need to select the resources we wish to analyze. Selecting Add resources gives us three options. Let’s first examine how we can select resources by identifying the account and resource type for analysis.
You can use Add resources by account dialog to choose resource types through a new interface. Here, we select All supported resource types and select the accounts we wish to monitor. This will create an analyzer that monitors all supported resource types. You can either select accounts through the organization structure (shown in the following screenshot) or paste in account IDs using the Enter AWS account ID option.
You can also choose to use the Define specific resource types dialog, which you can use to pick from a list of supported resource types (as shown in the following screenshot). By creating an analyzer with this configuration, IAM Access Analyzer will continually monitor both existing and new resources of the selected type within the account, checking for internal access.
After you’ve completed your selections, choose Add resources.
Alternatively, you can use the Add resources by resource ARN option.
Or you can use the Add resources by uploading a CSV file option to configure monitoring a list of specific resources at scale.
After you’ve completed the creation of your analyzer, IAM Access Analyzer will analyze policies daily and generate findings that show access granted to IAM roles and users within your organization. The updated IAM Access Analyzer dashboard now provides a resource-centric view. The Active findings section summarizes access into three distinct categories: public access, external access outside of the organization (requires creation of a separate external access analyzer), and access within the organization. The Key resources section highlights the top resources with active findings across the three categories. You can see a list of all analyzed resources by selecting View all active findings or Resource analysis on the left-hand navigation menu.
On the Resource analysis page, you can filter the list of all analyzed resources for further analysis.
When you select a specific resource, any available external access and internal access findings are listed on the Resource details page. Use this feature to evaluate all possible access to your selected resource. For each finding, IAM Access Analyzer provides you with detailed information about allowed IAM actions and their conditions, including the impact of any applicable SCPs and RCPs. This means you can verify that access is appropriately restricted and meets least-privilege requirements.
Pricing and availability
This new IAM Access Analyzer capability is available today in all commercial Regions. Pricing is based on the number of critical AWS resources monitored per month. External access analysis remains available at no additional charge. Pricing for EventBridge applies separately.
To learn more about IAM Access Analyzer and get started with analyzing internal access to your critical resources, visit the IAM Access Analyzer documentation.
Under pressure to do more with less? (Who isn’t, right?)
Whether you’re an IT leader or a startup founder, the last thing you want to do is waste time and money wrestling with expensive, overcomplicated cloud storage. According to a new report from Informa TechTarget’s Enterprise Strategy Group (ESG), you don’t have to. Backblaze B2 Cloud Storage delivers:
Up to 3.2x lower total cost of ownership (TCO)
Up to 56% lower monthly storage costs
Up to 92% less time and effort to manage data
Up to 100% lower download and transaction costs
Up to 91% savings on cloud to cloud (C2C) migration costs
Economic validation: Motivation, results, and methodology
The independent analysis confirms what many Backblaze B2 users already know: Our cloud storage platform is more affordable and easier to manage compared to legacy cloud providers like AWS, Google Cloud Platform, and Azure.
To develop these findings, the ESG analysts talked to customers. They validated use cases. They used our product and verified the accuracy of our listed pricing and cost calculator. And then, they took those results along with the knowledge they’ve gathered over decades of experience to quantify the benefits that organizations can expect by using the Backblaze B2 Cloud Storage platform.
Powerful storage, real savings
The ESG report highlights how Backblaze’s predictable pricing—including at least 3x free egress, if not totally free egress in many cases—can help businesses skip the painful math of legacy storage and start getting more value out of their data. Whether you’re hosting content, training AI models, backing up critical data, or building applications, B2 Cloud Storage gives you freedom without vendor lock-in.
It’s not just about saving money—it’s about reclaiming time and resources to focus on innovation.
Today, Amazon Web Services (AWS) announced that AWS Asia Pacific (Taipei) Region is generally available with three Availability Zones and Region code ap-east-2. The new Region brings AWS infrastructure and services closer to customers in Taiwan.
Skyline of Taipei including the Taipei 101 building
As the first infrastructure Region in Taipei and the fifteenth Region in Asia Pacific, the new Region expands the AWS global footprint to 117 Availability Zones across 37 geographic Regions worldwide. The new AWS Region will help developers, startups, and enterprises, as well as education, entertainment, financial services, healthcare, manufacturing, and nonprofit organizations run their applications and serve end users while maintaining data residency in Taiwan.
AWS in Taiwan
AWS has maintained a presence in Taiwan for more than a decade, starting with the opening of the AWS Taipei office in 2014. Since then, AWS has introduced many infrastructure offerings in Taiwan including:
In 2014, AWS launched the first Amazon CloudFront edge location and added another in 2018, offering customers a secure and efficient content delivery network for accelerating data, video, application, and API delivery worldwide.
In 2018, AWS established two AWS Direct Connect locations in Taiwan to enhance connectivity options. With the launch of the AWS Asia Pacific (Taipei) Region, we’ve added a new Direct Connect location in Taiwan to provide customers with higher speed and bandwidth.
In 2020, AWS launched AWS Outposts in Taiwan, helping customers seamlessly extend AWS infrastructure and services to their on-premises or edge locations for a consistent hybrid experience.
In 2022, AWS launched AWS Local Zone in Taipei to support low-latency applications requiring single-digit millisecond responsiveness.
Today, with the launch of the AWS Asia Pacific (Taipei) Region, we further strengthen our commitment to support innovation in Taiwan. Organizations in regulated industries will be able to store data locally while maintaining complete control over data location and movement. From high-tech manufacturing to semiconductor companies and small and medium enterprises (SMEs), businesses will gain access to the scalable infrastructure needed for growth and innovation.
AWS customers in Taiwan
Organizations across Taiwan are already using AWS to innovate and deliver differentiated experiences to their customers, for example:
Cathay Financial Holdings (CFH) is a leader in financial technology in Taiwan. It continuously introduces the latest technology to create a full-scenario financial service ecosystem. Since 2021, CFH has built a cloud environment on AWS that strengthens its security control and meets compliance requirements.
“Cathay Financial Holdings will continue to accelerate digital transformation in the industry, also improve the stability, security, timeliness, and scalability of our financial services,” said Marcus Yao, senior executive vice president of CFH. “With the new AWS Region in Taiwan, CFH is expected to provide customers with even more diverse and convenient financial services.”
Gamania Group is revolutionizing the entertainment landscape by integrating AI with celebrity IP through their innovative Vyin AI platform. Gamania utilized the robust and scalable infrastructure of AWS to develop secure, responsive AI interactions.
Benjamin Chen, chief strategy officer and head of Innovation Lab, said: “The core goal of Vyin AI is to create a digital identity that is fully interactive, lifelike, and safe to use. This demands technologies that are stable, responsive, and secure. To that end, we rely on the robust and resilient cloud infrastructure of AWS, and look forward to the low-latency advantages offered by the AWS Region in Taiwan. AWS provides a highly stable and secure environment for Vyin AI to provide users with secure and AI hallucination free interactions. AWS Cloud services allow us to focus more on core AI technology innovation and the enhancement of the ‘hyper-personalized interactive’ user experience, thereby accelerating product iteration and optimization.”
Chunghwa Telecom is a leader in cloud network services in Taiwan with the broadest mainstream 5G bandwidth, exceptional network speed, and globally recognized mobile internet capabilities. Chunghwa Telecom utilizes generative AI platforms such as Amazon Bedrock to build innovative services and create intelligent applications for various industries.
Dr. Rong-Shy Lin, president of CHT, stated: “With the launch of the AWS Region in Taiwan, CHT’s partnership with AWS has entered a new phase. We will deepen the integration of key advantages of the AWS Region, such as low latency and local data storage, combining them with CHT’s extensive backbone network, rich cloud experience, and professional team that has obtained multiple AWS Competency certifications. This will allow CHT to provide solutions that meet strict security and compliance requirements for government, financial, critical infrastructure, and highly regulated industries. At the same time, we are utilizing AWS technologies such as Amazon Bedrock to develop innovative applications and accelerate digital transformation and AI adoption. We will continue to provide optimized cloud and network services in Taiwan while supporting customers’ global expansion.”
AWS Partners in Taiwan
The AWS Partner Network in Taiwan plays a crucial role in helping customers adopt cloud technologies and maximize value from the new AWS Asia Pacific (Taipei) Region. These specialized partners combine deep technical expertise with local market knowledge to accelerate digital transformation across industries.
“eCloudvalley Group has always embraced our mission of being a cloud evangelist, driving the adoption of cloud technology across Taiwan’s industries,” said MP Tsai, chairman of eCloudvalley Group. “With over a decade of close collaboration with AWS, we are honored to help more and more customers and industries move to the cloud while being part of customers’ digital transformation journey on AWS. We believe that the launch of the AWS Asia Pacific (Taipei) Region will further support Taiwan companies’ digital transformation and innovation in Taiwan with its world-leading cloud technology, while industries with higher local data residency requirements, such as finance and healthcare, will be able to further advance their cloud transformation journey.”
“The investment of AWS in local infrastructure will help drive the digital transformation of Taiwan companies, boosting the development of various industries spanning from traditional industries to emerging digital sectors,” said Shasta Ho, the CEO of Nextlink Technology Inc. “We look forward to continuing working with AWS to help enterprises across industries deeply utilize the new AWS Asia Pacific (Taipei) Region. This local advantage will address customer needs in data localization, low latency, compliance, and high performance computing workloads. We also look forward to using AWS world-leading cloud technologies to power customers’ digital transformation journeys while contributing to the diversification of Taiwan’s economy.”
SAP has been a strategic partner of AWS for more than a decade, with thousands of enterprise customers worldwide running their SAP workloads on AWS.
“SAP is thrilled to see AWS establish new data centers in Taiwan,” said George Chen, SAP global vice president and managing director for Taiwan, Hong Kong, and Macau. “This investment provides Taiwan enterprises with greater choice, lower service latency, and enhanced operational flexibility. As a long-term strategic partner, SAP is committed to accelerating cloud transformation for these businesses. Through RISE with SAP, we can help customers seamlessly migrate to the cloud, enjoying greater flexibility, scalability, and reduced operational costs. By combining SAP’s enterprise solutions with the robust cloud platform of AWS, we’ll jointly empower Taiwan’s enterprises to unlock innovative AI applications and run their core businesses securely and reliably locally, driving Taiwan enterprise cloud transformation together.”
Supporting sustainable innovation in Taiwan
As Taiwan progresses toward its goal of net-zero emissions by 2050, AWS Cloud solutions are empowering organizations to enhance operational efficiency while reducing environmental impact. The new AWS Asia Pacific (Taipei) Region incorporates the AWS commitment to sustainability, helping organizations meet both technical and environmental objectives.
Ace Energy is a pioneer in Taiwan’s energy management sector. Since 2013, Ace Energy has been using AWS services such as Amazon Simple Storage Service (Amazon S3), Amazon Elastic Compute Cloud (Amazon EC2), and AWS IoT Core to provide innovative energy solutions through their Energy Saving Performance Contract model. Ace Energy has deployed energy management solutions across 1,000 locations, helped a semiconductor manufacturer reduce steam consumption by 65 percent, achieved 22 million new Taiwan dollars in annual energy savings, and decreased carbon emissions by 8,000 tons through their waste heat recovery technology.
Taiwan Power Company (Taipower) is Taiwan’s state power utility and has revolutionized its operations through AWS since 2018. By implementing smart grid technologies with drones, robotics, and virtual reality for smart patrol, Taipower has enhanced customer experience through the “Taiwan Power” application. The company has improved operational efficiency through data-driven decision-making and earned six consecutive Platinum Awards in the Corporate Sustainability category at the Taiwan Corporate Sustainability Awards.
Building cloud skills together
Since 2014, AWS has built comprehensive programs for cloud education and skills development in Taiwan. For example, educational programs such as AWS Academy, AWS Educate, and AWS Skill Builder have helped train more than 200,000 people in Taiwan on cloud skills. These programs will expand alongside our infrastructure investments to build a foundation for Taiwan’s digital future.
Taiwan boasts a vibrant AWS community that welcomes your involvement. Take part in knowledge-sharing and networking at local AWS User Groups in Taipei, engage with the four celebrated AWS Heroes in Taiwan, or consider becoming part of the growing community of AWS enthusiasts by joining the ranks of the 17 AWS Community Builders already contributing to Taiwan’s cloud ecosystem. All these community connections provide valuable opportunities to accelerate your cloud journey through local expertise and collaborative learning.
Stay tuned The AWS Asia Pacific (Taipei) Region is ready to support your business. You can find a detailed list of the services available in this Region on the AWS Services by Region page. For news about AWS Region openings, check out the Regional news of the AWS News Blog.
Start building on the Asia Pacific (Taipei) Region now.
Today, we’re announcing a new publicly available source of API models for Amazon Web Services (AWS). We are now publishing AWS API models on a daily basis to Maven Central and providing open source access to a new repository on GitHub. This repository includes a definitive, up-to-date source of Smithy API models that define AWS public interface definitions and behaviors.
These Smithy models can be used to better understand AWS services and build developer tools like custom software development kits (SDK) and command line interfaces (CLIs) for connecting to AWS or testing tools for validating your application integrations on AWS.
Since 2018, we have been generating SDK clients and CLI tools using Smithy models. All AWS services are modeled in Smithy to thoroughly document the API contract including operations and behaviors like protocols, authentication, request and response types, and errors.
With this public resource, you can build and test your own applications that can integrate directly with AWS services with confidence such as:
Generating API implementations – You can generate server stubs for language-specific framework, even model context protocol (MCP) server configurations for your AI agents. You have built-in validation to ensure you adhere to your own API standards.
Build your own developer tools – You can build your own tools on top of AWS such as mock testing tools, IAM policy generators, or higher-level abstractions for connecting to AWS.
Understand AWS API behaviors – You can concisely and easily investigate your artifact to quickly review and understand how SDKs interpret API calls and the behaviors to expect with those calls.
Learn about AWS API models You can browse the AWS service models directly on GitHub by accessing the api-models-aws repository. This repository contains Smithy models with the JSON AST format for all public AWS API services. All Smithy models consist of shapes and traits. Shapes are instances of types and traits are used to add more information to shapes that might be useful for clients, servers, or documentation.
The AWS models repository contains:
Top-level service directories are named using the <sdk-id> of the service, where <sdk-id> is the value of the model’s sdkId, lowercased and with spaces converted to hyphens
Each service directory contains one directory per <version> of the service, where <version> is the value of the service shape’s version property.
Contained within a service-version directory, a model file named <sdk-id>-<version>.json will be present
For example, when you want to define a RunInstances API in Amazon EC2 service, the model uses service type, an entry point of an API that aggregates resources and operations together. The shape referenced by a member is called its target.
The operation type represents the input, output, traits, and possible errors of an API operation. Operation shapes are bound to resource shapes and service shapes. An operation is defined in the IDL using an operation_statement. In the traits, you can find detailed API information such as documentation, examples, and so on.
"com.amazonaws.ec2#RunInstances": {
      "type": "operation",
      "input": {
        "target": "com.amazonaws.ec2#RunInstancesRequest"
      },
      "output": {
        "target": "com.amazonaws.ec2#Reservation"
      },
      "traits": {
        "smithy.api#documentation": "<p>Launches the specified number of instances using an AMI for which you have....",
        smithy.api#examples": [
          {
            "title": "To launch an instance",
            "documentation": "This example launches an instance using the specified AMI, instance type, security group, subnet, block device mapping, and tags.",
            "input": {
              "BlockDeviceMappings": [
                {
                  "DeviceName": "/dev/sdh",
                  "Ebs": {
                    "VolumeSize": 100
                  }
                }
              ],
              "ImageId": "ami-abc12345",
              "InstanceType": "t2.micro",
              "KeyName": "my-key-pair",
              "MaxCount": 1,
              "MinCount": 1,
              "SecurityGroupIds": [
                "sg-1a2b3c4d"
              ],
              "SubnetId": "subnet-6e7f829e",
              "TagSpecifications": [
                {
                  "ResourceType": "instance",
                  "Tags": [
                    {
                      "Key": "Purpose",
                      "Value": "test"
                    }
                  ]
                }
              ]
            },
            "output": {}
          }
        ]
      }
    },
We use Smithy extensively to model our service APIs and provide the daily releases of the AWS SDKs and AWS CLI. AWS API models can be helpful for implementing server stubs to interact with AWS services.
How to build with AWS API models Smithy API models provide building resources such as build tools, client or server code generators, IDE support, and implementations. For example, with Smithy CLI, you can easily build your models, run ad-hoc validation, compare models for differences, query models, and more. The Smithy CLI makes it easy to get started working with Smithy without setting up Java or using the Smithy Gradle Plugins.
I want to show two examples how to build your own applications with AWS API models and Smithy build tools.
Build a minimal SDK client – This sample project provides a template to get started using Smithy TypeScript to create a minimal AWS SDK client for Amazon DynamoDB. You can build the minimal SDK from the Smithy model, and then run the example code. To learn more, visit the example project here.
Build MCP servers – This sample project provides a template to generate a fat jar which contains all the dependencies required to run a MCP StdIO server using the Smithy CLI. You can find MCPServerExample to build an MCP server by modeling tools as Smithy APIs and ProxyMCPExample to create a proxy MCP Server for any Smithy service. To learn more, visit the GitHub repository.
Now available You can now access AWS API models on a daily basis providing open-source access on the AWS API models repository and service model packages available on Maven Central. You can import models and add dependencies using the maven package of their choice.
Customers across industries are harnessing the power of generative AI on AWS to boost employee productivity, deliver exceptional customer experiences, and streamline business processes. However, the growth in demand for GPU capacity has outpaced industry-wide supply, making GPUs a scarce resource and increasing the cost of securing them.
As Amazon Web Services (AWS) grows, we work hard to lower our costs so that we can pass those savings back to our customers. Regular price reductions on AWS services have been a standard way for AWS to pass on the economic efficiencies gained from our scale back to our customers.
Today, we’re announcing up to 45 percent price reduction for Amazon Elastic Compute Cloud (Amazon EC2) NVIDIA GPU-accelerated instances: P4 (P4d and P4de) and P5 (P5 and P5en) instance types. This price reduction to On-Demand and Savings Plan pricing applies to all Regions where these instances are available. The pricing reduction applies to On-Demand purchases beginning June 1 and to Savings Plan purchases effective after June 4.
Here is a table of price reductions percentage (%) from May 31, 2025 baseline prices by instance types and pricing plans:
Instance type
NVIDIA GPUs
On-Demand
EC2 Instance Savings Plans
Compute Savings Plans
1 year
3 years
1 year
3 years
P4d
A100
33%
31%
25%
31%
–
P4de
A100
33%
31%
25%
31%
–
P5
H100
44%
–
45%
44%
25%
P5en
H200
25%
–
26%
25%
–
Savings Plans are a flexible pricing model that offer low prices on compute usage, in exchange for a commitment to a consistent amount of usage (measured in $/hour) for a 1- or 3- year term. We offers two types of Savings Plans:
EC2 Instance Savings Plans provide the lowest prices, offering savings in exchange for commitment to usage of individual instance families in a Region (for example, P5 usage in the US (N. Virginia) Region).
Compute Savings Plans provide the most flexibility and help to reduce your costs regardless of instance family, size, Availability Zones, and Regions (for example, from P4d to P5en instances, shift a workload between US Regions).
To provide increased accessibility to reduced pricing, we are making at-scale On-Demand capacity available for:
P4d instances in the Asia Pacific (Seoul), Asia Pacific (Sydney), Canada (Central), and Europe (London) Regions
P4de instances in the US East (N. Virginia) Region
P5 instances in the Asia Pacific (Mumbai), Asia Pacific (Tokyo), Asia Pacific (Jakarta), and South America (São Paulo) Regions
P5en instances in the Asia Pacific (Mumbai), Asia Pacific (Tokyo), and Asia Pacific (Jakarta) Regions
We are also now delivering Amazon EC2 P6-B200 instances through Savings Plan to support large scale deployments, which became available on May 15, 2025 at launch only through EC2 Capacity Blocks for ML. EC2 P6-B200 instances, powered by NVIDIA Blackwell GPUs, accelerate a broad range of GPU-enabled workloads but are especially well-suited for large-scale distributed AI training and inferencing.
These pricing updates reflect the AWS commitment to making advanced GPU computing more accessible while passing cost savings directly to customers.
Give Amazon EC2 NVIDIA GPU-accelerated instances a try in the Amazon EC2 console. To learn more about these pricing updates, visit Amazon EC2 Pricing page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.
AI workloads don’t play by the same rules as your average enterprise app, and if you’ve looked at your cloud bill lately, you probably know that already. They have unique demands that make them especially vulnerable to hidden AI storage costs. Think: massive parallel GPU training, nonstop data shuffling, and frequent checkpointing.
The problem? Most cloud pricing models weren’t built for this kind of action. They were designed when workloads were a lot more predictable. So, when you run AI workloads on storage models built by hyperscalers, the costs add up quickly, and often invisibly.
Download the ebook
Struggling to keep AI storage costs under control? Download our free ebook to discover how to optimize cloud storage for AI workloads—without compromising performance.
Here are five reasons your cloud bill for AI workloads could spiral out of control:
1. Death by API call: Soaring costs in AI training pipelines.
AI workloads are packed with transactions. Every ingest of raw data, training round, inference batch, or logging step triggers API calls—PUTs, GETs, LISTs, and COPYs. If you’re training a foundational model like Deepseek v3 or Llama 2, you could be making millions of small transactions a day just by uploading all the raw data you require for training.
Each transaction might cost a fraction of a cent—but they add up.
Example: Let’s assume a model needs 1 trillion pretraining tokens. Different data sources contribute varying numbers of tokens per file. For this exercise, let’s assume the following token counts:
Web pages: ~1,000 tokens/page (e.g., blog posts, articles)
A typical large language model (LLM) training mix might look like this:
Source
% of tokens
Tokens contribution
Files required (approx.)
Web pages
40%
400B tokens
400M files
Books
20%
200B tokens
2M files
Code
15%
150B tokens
300M files
News articles
15%
150B tokens
187.5M files
Academic papers
10%
100B tokens
20M files
Total
100%
1T tokens
~909.5M files
If you’re ingesting 909.5 million files to AWS S3 at $0.005 per 1,000 PUTs (pricing as of April 2025), then you’d be charged:
909,500,000 ÷ 1,000 = 909,500 units
909,500 × $0.005 = $4,547.50
That’s $4,547.50 in just PUT transaction fees—for just collecting all the data you need for training. And that’s not counting GETs, LISTs, or any other operations that are necessary to support the full AI data pipeline.
2. The small file tax: How small files drive up AI cloud storage costs
Models trained on image slices, text tokens, or time-series data can create millions of small files. These not only trigger excessive API calls, but also suffer from the following:
Some providers bill you by minimum object size (e.g., rounding all small files up to 128KB).
Every small object can trigger a full-priced transaction.
Frequent access means you’re paying for reads, not just storage.
This mismatch means your dataset of 100 million 10KB files could behave (and cost) like a much larger, high-churn workload.
3. Why cold storage fails for AI data workloads
Deep archive tiers may be cheap upfront, but they’re a poor fit for iterative AI workflows. Need to rehydrate training data to rerun a model? Get ready to wait hours and pay per retrieval. Need to delete? You could get hit with minimum retention penalties, and pay for that data as if you held onto it for 60, 90, or even 180 days.
AI workflows are iterative. You’re not archiving log files; you’re experimenting, fine-tuning, and reprocessing constantly. Cold storage is rarely compatible with that.
4. Egress fees: The hidden cost of moving AI training data
Egress is a silent killer. It’s the fee you pay every time you move data out of cloud storage. In AI workflows, that’s often necessary for:
Sending training data to a GPU cluster.
Validating models on a local system.
Migrating to another provider.
Collaborating with partners across clouds or regions.
These fees scale linearly with data volume, which is a problem when your AI pipeline is pulling terabytes or petabytes per day.
5. AI data lifecycle rules can backfire
You might set up lifecycle rules to move infrequently accessed data to cheaper tiers—sounds smart, right?
Except:
Lifecycle transitions often come with per-object fees.
Accessing those objects later triggers retrieval fees, or breaks performance expectations.
Deleting or overwriting too early triggers penalties.
And all of this assumes you even know your data’s “temperature” in advance—which, in AI workflows, changes day to day.
Smarter AI Storage
Your AI pipeline isn’t just a compute problem: It’s a data movement and storage orchestration engine. And that’s exactly where traditional cloud pricing models fall short.
If your cloud bill is blowing up, it’s probably not just because you kicked off another training run. It’s the millions of GET requests, the silent egress charges, and those archive tier retrievals you didn’t plan for.
The good news? Once you know where the hidden costs are, you can start building smarter.
Seismic imaging is a geophysical technique used to create detailed pictures of the Earth’s subsurface structure. It works by generating seismic waves that travel into the ground, reflect off various rock layers and structures, and return to the surface where they’re detected by sensitive instruments known as geophones or hydrophones. The huge volumes of acquired data often reach petabytes for a single survey and this presents significant storage, processing, and management challenges for researchers and energy companies.
Customers who run these seismic imaging workloads or other high performance computing (HPC) workloads, such as weather forecasting, advanced driver-assistance system (ADAS) training, or genomics analysis, already store the huge volumes of data on either hard disk drive (HDD)-based or a combination of HDD and solid state drive (SSD) file storage on premises. However, as these on premises datasets and workloads scale, customers find it increasingly challenging and expensive due to the need to make upfront capital investments to keep up with performance needs of their workloads and avoid running out of storage capacity.
Today, we’re announcing the general availability of the Amazon FSx for Lustre Intelligent-Tiering, a new storage class that delivers virtually unlimited scalability, the only fully elastic Lustre file storage, and the lowest cost Lustre file storage in the cloud. With a starting price of less than $0.005 per GB-month, FSx for Lustre Intelligent-Tiering offers the lowest cost high-performance file storage in the cloud, reducing storage costs for infrequently accessed data by up to 96 percent compared to other managed Lustre options. Elasticity means you no longer need to provision storage capacity upfront because your file system will grow and shrink as you add or delete data, and you pay only for the amount of data you store.
FSx for Lustre Intelligent-Tiering automatically optimizes costs by tiering cold data to the applicable lower-cost storage tier based on access patterns and includes an optional SSD read cache to improve performance for your most latency sensitive workloads. Intelligent-Tiering delivers high performance whether you’re starting with gigabytes of experimental data or working with large petabyte-scale datasets for your most demanding artificial intelligence/machine learning (AI/ML) and HPC workloads. With the flexibility to adjust your file system’s performance independent of storage, Intelligent-Tiering delivers up to 34 percent better price performance than on premises HDD file systems. The Intelligent-Tiering storage class is optimized for HDD-based or mixed HDD/SSD workloads that have a combination of hot and cold data. You can migrate and run such workloads to FSx for Lustre Intelligent-Tiering without application changes, eliminating storage capacity planning and management, while paying only for the resources that you use.
Prior to this launch, customers used the FSx for Lustre SSD storage class to accelerate ML and HPC workloads that need all-SSD performance and consistent low-latency access to all data. However, many workloads have a combination of hot and cold data and they don’t need all-SSD storage for colder portions of the data. FSx for Lustre is increasingly used in AI/ML workloads to increase graphics processing unit (GPU) utilization, and now it’s even more cost optimized to be one of the options for these workloads.
FSx for Lustre Intelligent-Tiering Your data moves between three storage tiers (Frequent Access, Infrequent Access, and Archive) with no effort on your part, so you get automatic cost savings with no upfront costs or commitments. The tiering works as follows:
Frequent Access – Data that has been accessed within the last 30 days is stored in this tier.
Infrequent Access – Data that hasn’t been accessed for 30 – 90 days is stored in this tier, at a 44 percent cost reduction from Frequent Access.
Archive – Data that hasn’t been accessed for 90 or more days is stored in this tier, at a 65 percent cost reduction compared to Infrequent Access.
Regardless of the storage tier, your data is stored across multiple AWS Availability Zones for redundancy and availability, compared to typical on-premises implementations, which are usually confined within a single physical location. Additionally, your data can be retrieved instantly in milliseconds.
Now, it’s time to enter the rest of the information to create the file system. I enter a name (veliswa_fsxINT_1) for my file system, and for deployment and storage class, I select Persistent, Intelligent-Tiering. I choose the desired Throughput capacity and the Metadata IOPS. The SSD read cache will be automatically configured by FSx for Lustre based on the specified throughput capacity. I leave the rest as the default, choose Next, and review my choices to create my file system.
With Amazon FSx for Lustre Intelligent-Tiering, you have the flexibility to provision the necessary performance for your workloads without having to provision any underlying storage capacity upfront.
I wanted to know which values were editable after creation, so I paid closer attention before finalizing the creation of the file system. I noted that Throughput capacity, Metadata IOPS, Security groups, SSD read cache, and a few others were editable later. After I start running the ML jobs, it might be necessary to increase the throughput capacity based on the volumes of data I’ll be processing, so this information is important to me.
The file system is now available. Considering that I’ll be running HPC workloads, I anticipate that I’ll be processing high volumes of data later, so I’ll increase the throughput capacity to 24 GB/s. After all, I only pay for the resources I use.
The SSD read cache is scaled automatically as your performance needs increase. You can adjust the cache size any time independently in user-provisioned mode or disable the read cache if you don’t need low-latency access.
Good to know
FSx for Lustre Intelligent-Tiering is designed to deliver up to multiple terabytes per second of total throughput.
FSx for Lustre with Elastic Fabric Adapter (EFA)/GPU Direct Storage (GDS) support provides up to 12x (up to 1200 Gbps) higher per-client throughput compared to the previous FSx for Lustre systems.
It can deliver up to tens of millions of IOPS for writes and cached reads. Data in the SSD read cache has submillisecond time-to-first-byte latencies, and all other data has time-to-first-byte latencies in the range of tens of milliseconds.
Now available Here are a couple of things to keep in mind:
FSx Intelligent-Tiering storage class is available in the new FSx for Lustre file systems in the US East (N. Virginia, Ohio), US West (N. California, Oregon), Canada (Central), Europe (Frankfurt, Ireland, London, Stockholm), and Asia Pacific (Hong Kong, Mumbai, Seoul, Singapore, Sydney, Tokyo) AWS Regions.
You pay for data and metadata you store on your file system (GB/months). When you write data or when you read data that is not in the SSD read cache, you pay per operation. You pay for the total throughput capacity (in MBps/month), metadata IOPS (IOPS/month), and SSD read cache size for data and metadata (GB/month) you provision on your file system. To learn more, visit the Amazon FSx for Lustre Pricing page. To learn more about Amazon FSx for Lustre including this feature, visit the Amazon FSx for Lustre page.
(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)
In an earlier blog post, I explained how to build your own LLM with Backblaze B2 + Jupyter Notebook, implementing a simple conversational AI chatbot using the LangChain AI framework to implement retrieval-augmented generation (RAG). The notebook walks you through the process of loading PDF files from a Backblaze B2 Bucket into a vector store, running a local instance of a large language model (LLM) and combining those to form a chatbot that can answer questions on its specialist subject.
That article generated a lot of interest, and a few questions:
“Could you make this into a web app, like ChatGPT?”
“Could you use this with OpenAI? DeepSeek?”
“Could I load multiple collections of documents into this?”
“Could I run multiple LLMs and compare them?”
“Can I add new documents to the vector store as they are uploaded to the bucket?”
The answer to all of these questions is “Yes!”
Today, I’ll present a simple conversational AI chatbot web app with a ChatGPT-style UI that you can easily configure to work with OpenAI, DeepSeek, or any of a range of other LLMs. In future blog posts, I’ll extend this to allow you to configure multiple LLMs and document collections, and integrate with Backblaze B2’s Event Notifications feature to load documents into the vector store within seconds of them being uploaded.
And, here’s a very short video of the chatbot in action:
Retrieval-augmented generation, or RAG for short, is a technique that applies the generative features of an LLM to a collection of documents, resulting in a chatbot that can effectively answer questions based on the content of those documents.
A typical RAG implementation splits each document in the collection into a number of roughly equal-sized, overlapping chunks, and generates an embedding for each chunk. Embeddings are vectors (lists) of floating point numbers with hundreds or thousands of dimensions. The distance between two vectors indicates their similarity. Small distances indicate high similarity and large distances indicate low similarity.
The RAG app then loads each chunk, along with its embedding, into a vector store. The vector store is a special-purpose database that can perform a similarity search–given a piece of text, the vector store can retrieve chunks ranked by their similarity to the query text by comparing the embeddings.
Let’s put the pieces together:
Given a question from the user (1), the RAG app can query the vector store for chunks of text that are similar to the question (2). This will be the context that helps the LLM answer the user’s question. Here’s a concrete example using the Backblaze documentation collection: Given the question, “Tell me about object lock,” the vector store returns four document chunks, each of about 170 words, to the app (3). Here is a link to the text of, and a short extract from, each chunk:
Object Lock: With Object Lock Legal Hold, files are prevented from being changed or deleted, but the immutability does not have a defined retention period.
Object Lock: You can enable Object Lock on a bucket when you create a new bucket or on an existing bucket.
Object Lock: Object Lock in Backblaze B2 was designed with the Immutability feature in Veeam Backup & Replication in mind.
Enable Object Lock with the S3 Compatible API: To enable Object Lock on an existing S3 compatible bucket, add the x-amz-bucket-object-lock-token header with a value of 1 to the S3 Put Object Lock Configuration API call.
Unsurprisingly, three of the four results are extracts from the main documentation article on Object Lock.
In order to provide a conversational experience, the RAG app maintains a chat history in a message store. The RAG app retrieves the message history (4) to form part of the query it will send to the LLM.
A system prompt sets the guidelines for the LLM to generate responses. In a RAG, the system prompt typically specifies that the response should be based on retrieved document data rather than model memorization, and attempts to prevent hallucinations by ensuring that the model does not fabricate information if no relevant documents are found. Here is the system prompt from the RAG app:
Use the following pieces of context and the message history to answer the question at the end. If you don't know the answer, just say that you don't know, don't try to make up an answer.
The RAG submits the system prompt, the context, the last few messages in the conversation, and the user’s question to the LLM (5), which generates a, hopefully useful, response (6). Here’s the answer it provided to the above question:
Object Lock is a feature that allows users to enforce immutability on files stored in cloud storage, specifically in services like Backblaze B2 and AWS S3. Here are the key points about Object Lock:
Immutability: Once a file is locked, it cannot be modified or deleted until a specified retention period expires or a legal hold is lifted.
Retention Periods: Users can set a retention period when locking a file. During this time, the file remains immutable, meaning it cannot be changed or deleted.
Legal Hold: Users can place files under a legal hold, which prevents modifications or deletions indefinitely until the hold is removed.
Enabling Object Lock: Object Lock can be enabled for new buckets or existing ones, but it must be turned on at the bucket level before files are uploaded.
Integrations: Some applications, like Veeam Backup & Replication, offer built-in support for Object Lock, making the process easier for users when they want to ensure file immutability during backups.
No Extra Cost: There is no additional fee for using Object Lock; however, standard storage charges for the locked files still apply.
Mistakes in Locking: If a user locks a file for longer than intended, they may need to contact support to resolve the situation, which could involve closing their storage account in some cases.
Overall, Object Lock is a crucial feature for organizations that need to ensure data integrity and compliance with regulations concerning data retention.
The RAG app adds the user’s question and the LLM’s response to the message store (7), returns the answer to the user (8), and awaits the next question.
A quick tour of the sample app
The sample app is on GitHub at https://github.com/backblaze-b2-samples/ai-rag-app. The app is open source, under the MIT license, so you can use it as a basis for your own experimentation without any restrictions. The app was originally written to demonstrate RAG with Backblaze B2 Cloud Storage, but it works with any S3 compatible object store.
The README file covers configuration and deployment in some detail; in this blog post, I’ll just give you a high-level overview. The sample app is written in Python using the Django web framework. API credentials and related settings are configured via environment variables, while the LLM and vector store are configured via Django’s settings.py file:
# Change source_data_location and vector_store_location to match your environment # search_k is the number of results to return when searching the vector store DOCUMENT_COLLECTION: CollectionSpec = { 'name': 'Docs', 'source_data_location': 's3://blze-ev-ai-rag-app/pdfs', 'vector_store_location': 's3://blze-ev-ai-rag-app/vectordb/docs/openai', 'search_k': 4, 'embeddings': { 'cls': OpenAIEmbeddings, 'init_args': { 'model': "text-embedding-3-large", }, }, }
The sample app is configured to use OpenAI GPT-4o mini, but the README explains how to use different online LLMs such as DeepSeek V3 or Google Gemini 2.0 Flash, or even a local LLM such as Meta Llama 3.1 via the Ollama framework. If you do run a local LLM, be sure to pick a model that fits your hardware. I tried running Meta’s Llama 3.3, which has 70 billion parameters (70B), on my MacBook Pro with the M1 Pro CPU. It took nearly three hours to answer a single question! Llama 3.1 8B was a much better fit, answering questions in less than 30 seconds.
Notice that the document collection is configured with the location of a vector store containing the Backblaze documentation as a sample dataset. The README file contains an application key with read-only access to the PDFs and vector store so you can try the application without having to load your own set of documents.
If you want to use your own document collection, a pair of custom commands allow you to load them from a Backblaze B2 Bucket into the vector store and then query the vector store to test that it all worked.
First, you need to load your data:
% python manage.py load_vector_store
Deleting existing LanceDB vector store at s3://blze-ev-ai-rag-app/vectordb/docs
Creating LanceDB vector store at s3://blze-ev-ai-rag-app/vectordb/docs
Loading data from s3://blze-ev-ai-rag-app/pdfs in pages of 1000 results
Successfully retrieved page 1 containing 618 result(s) from s3://blze-ev-ai-rag-app/pdfs
Skipping pdfs/.bzEmpty
Skipping pdfs/cloud_storage/.bzEmpty
Loading pdfs/cloud_storage/cloud-storage-about-backblaze-b2-cloud-storage.pdf
Loading pdfs/cloud_storage/cloud-storage-add-file-information-with-the-native-api.pdf
Loading pdfs/cloud_storage/cloud-storage-additional-resources.pdf
...
Loading pdfs/v1_api/s3-put-object.pdf
Loading pdfs/v1_api/s3-upload-part-copy.pdf
Loading pdfs/v1_api/s3-upload-part.pdf
Loaded batch of 614 document(s) from page
Split batch into 2758 chunks
[2025-02-28T01:26:11Z WARN  lance_table::io::commit] Using unsafe commit handler. Concurrent writes may result in data loss. Consider providing a commit handler that prevents conflicting writes.
Added chunks to vector store
Added 614 document(s) containing 2758 chunks to vector store; skipped 4 result(s).
Created LanceDB vector store at s3://blze-ev-ai-rag-app/vectordb/docs. "vectorstore" table contains 2758 rows
Now you can verify that the data is stored by querying the vector store. Notice how the raw results from the vector store include an S3 URI identifying the source document:
% python manage.py search_vector_store 'Which B2 native APIs would I use to upload large files?'
2025-03-01 02:38:07,740 ai_rag_app.management.commands.search INFO     Opening vector store at s3://blze-ev-ai-rag-app/vectordb/docs/openai
2025-03-01 02:38:07,740 ai_rag_app.utils.vectorstore DEBUG    Populating AWS environment variables from the b2 profile
Found 4 docs in 2.30 seconds
2025-03-01 02:38:11,074 ai_rag_app.management.commands.search INFO
page_content='Parts of a large file can be uploaded and copied in parallel, which can significantly reduce the time it takes to upload terabytes of data. Each part can be  anywhere from 5 MB to 5 GB, and you can pick the size that is most convenient for your application. For best upload performance, Backblaze recommends that you use the recommendedPartSize parameter that is returned by the b2_authorize_account operation.  To upload larger files and data sets, you can use the command-line interface (CLI), the Native API, or an integration, such as Cyberduck.  Usage for Large Files  Generally, large files are treated the same as small files. The costs for the API calls are the same.  You are charged for storage for the parts that you uploaded or copied. Usage is counted from the time the part is stored. When you call the b2_finish_large_file' metadata={'source': 's3://blze-ev-ai-rag-app/pdfs/cloud_storage/cloud-storage-large-files.pdf'}
...
The core of the sample application is the RAG class. There are several methods that create the basic components of the RAG, but here we’ll look at how the _create_chain() method brings together the system prompt, vector store, message history, and LLM.
First, we define the system prompt, which includes a placeholder for the context—those chunks of text that the RAG will retrieve from the vector store:
# These are the basic instructions for the LLM
system_prompt = (
    "Use the following pieces of context and the message history to "
    "answer the question at the end. If you don't know the answer, "
    "just say that you don't know, don't try to make up an answer. "
    "\n\n"
    "Context: {context}"
)
Then we create a prompt template that brings together the system prompt, message history, and the user’s question:
# The prompt template brings together the system prompt, context, message history and the user's question
prompt_template = ChatPromptTemplate(
    [
        ("system", system_prompt),
        MessagesPlaceholder(variable_name="history", optional=True, n_messages=10),
        ("human", "{question}"),
    ]
)
Now we use LangChain Expression Language (LCEL) to bring the various components together to form a chain. LCEL allows us to define a chain of components declaratively; that is, we provide a high-level representation of the chain we want, rather than specifying how the components should fit together.
Notice the log_data() helper method—it simply logs its input and passes it on to the next component in the chain.
# Create the basic chain
# When loglevel is set to DEBUG, log_input will log the results from the vector store
chain = (
    {
        "context": (
            itemgetter("question")
            | retriever
            | log_data('Documents from vector store', pretty=True)
        ),
        "question": itemgetter("question"),
        "history": itemgetter("history"),
    }
    | prompt_template
    | model
    | log_data('Output from model', pretty=True)
)
Assigning a name to the chain allows us to add instrumentation when we invoke it:
# Give the chain a name so the handler can see it
named_chain: Runnable[Input, Output] = chain.with_config(run_name="my_chain")
Now, we use LangChain’s RunnableWithMessageHistory class to manage adding and retrieving messages from the message store:
The input to the chain is a Python dictionary containing the question, while the config argument configures the chain with the Django session key and a callback that annotates the chain output with its execution time. Since the chain output contains Markdown formatting, the API endpoint that handles requests from the front end uses the open source markdown-it library to render the output to HTML for display.
The remainder of the code is mostly concerned with rendering the web UI. One interesting facet is that the Django view, responsible for rendering the UI as the page loads, uses the RAG’s message store to render the conversation, so if you reload the page, you don’t lose your context.
Take this code and run it!
The sample AI RAG application is open source under the MIT license, and I encourage you to use it as the basis for your own RAG exploration. The README file suggests a few ways you could extend it, and I also draw your attention to conclusion of the README if you are thinking of running the app in production:
[…] in order to get you started quickly, we streamlined the application in several ways. There are a few areas to attend to if you wish to run this app in a production setting:
The app does not use a database for user accounts, or any other data, so there is no authentication. All access is anonymous. If you wished to have users log in, you would need to restore Django’s AuthenticationMiddleware class to the MIDDLEWARE configuration and configure a database.
Similarly, conversation history is stored in memory, so you would need to use a persistent message history implementation, such as RedisChatMessageHistory to run the app in multiple processes or on multiple hosts.
Above all, have fun! AI is a rapidly evolving technology, with vendors and open source projects releasing new capabilities every day. I hope you find this app a useful way of jumping in.
Anthropic launched the next generation of Claude models today—Opus 4 and Sonnet 4—designed for coding, advanced reasoning, and the support of the next generation of capable, autonomous AI agents. Both models are now generally available in Amazon Bedrock, giving developers immediate access to both the model’s advanced reasoning and agentic capabilities.
Amazon Bedrock expands your AI choices with Anthropic’s most advanced models, giving you the freedom to build transformative applications with enterprise-grade security and responsible AI controls. Both models extend what’s possible with AI systems by improving task planning, tool use, and agent steerability.
With Opus 4’s advanced intelligence, you can build agents that handle long-running, high-context tasks like refactoring large codebases, synthesizing research, or coordinating cross-functional enterprise operations. Sonnet 4 is optimized for efficiency at scale, making it a strong fit as a subagent or for high-volume tasks like code reviews, bug fixes, and production-grade content generation.
When building with generative AI, many developers work on long-horizon tasks. These workflows require deep, sustained reasoning, often involving multistep processes, planning across large contexts, and synthesizing diverse inputs over extended timeframes. Good examples of these workflows are developer AI agents that help you to refactor or transform large projects. Existing models may respond quickly and fluently, but maintaining coherence and context over time—especially in areas like coding, research, or enterprise workflows—can still be challenging.
Claude Opus 4 Claude Opus 4 is the most advanced model to date from Anthropic, designed for building sophisticated AI agents that can reason, plan, and execute complex tasks with minimal oversight. Anthropic benchmarks show it is the best coding model available on the market today. It excels in software development scenarios where extended context, deep reasoning, and adaptive execution are critical. Developers can use Opus 4 to write and refactor code across entire projects, manage full-stack architectures, or design agentic systems that break down high-level goals into executable steps. It demonstrates strong performance on coding and agent-focused benchmarks like SWE-bench and TAU-bench, making it a natural choice for building agents that handle multistep development workflows. For example, Opus 4 can analyze technical documentation, plan a software implementation, write the required code, and iteratively refine it—while tracking requirements and architectural context throughout the process.
Claude Sonnet 4 Claude Sonnet 4 complements Opus 4 by balancing performance, responsiveness, and cost, making it well-suited for high-volume production workloads. It’s optimized for everyday development tasks with enhanced performance, such as powering code reviews, implementing bug fixes, and new feature development with immediate feedback loops. It can also power production-ready AI assistants for near real-time applications. Sonnet 4 is a drop-in replacement from Claude Sonnet 3.7. In multi-agent systems, Sonnet 4 performs well as a task-specific subagent—handling responsibilities like targeted code reviews, search and retrieval, or isolated feature development within a broader pipeline. You can also use Sonnet 4 to manage continuous integration and delivery (CI/CD) pipelines, perform bug triage, or integrate APIs, all while maintaining high throughput and developer-aligned output.
Opus 4 and Sonnet 4 are hybrid reasoning models offering two modes: near-instant responses and extended thinking for deeper reasoning. You can choose near-instant responses for interactive applications, or enable extended thinking when a request benefits from deeper analysis and planning. Thinking is especially useful for long-context reasoning tasks in areas like software engineering, math, or scientific research. By configuring the model’s thinking budget—for example, by setting a maximum token count—you can tune the tradeoff between latency and answer depth to fit your workload.
How to get started To see Opus 4 or Sonnet 4 in action, enable the new model in your AWS account. Then, you can start coding using the Bedrock Converse API with model IDanthropic.claude-opus-4-20250514-v1:0 for Opus 4 and anthropic.claude-sonnet-4-20250514-v1:0 for Sonnet 4. We recommend using the Converse API, because it provides a consistent API that works with all Amazon Bedrock models that support messages. This means you can write code one time and use it with different models.
For example, let’s imagine I write an agent to review code before merging changes in a code repository. I write the following code that uses the Bedrock Converse API to send a system and user prompts. Then, the agent consumes the streamed result.
private let modelId = "us.anthropic.claude-sonnet-4-20250514-v1:0"

// Define the system prompt that instructs Claude how to respond
let systemPrompt = """
You are a senior iOS developer with deep expertise in Swift, especially Swift 6 concurrency. Your job is to perform a code review focused on identifying concurrency-related edge cases, potential race conditions, and misuse of Swift concurrency primitives such as Task, TaskGroup, Sendable, @MainActor, and @preconcurrency.

You should review the code carefully and flag any patterns or logic that may cause unexpected behavior in concurrent environments, such as accessing shared mutable state without proper isolation, incorrect actor usage, or non-Sendable types crossing concurrency boundaries.

Explain your reasoning in precise technical terms, and provide recommendations to improve safety, predictability, and correctness. When appropriate, suggest concrete code changes or refactorings using idiomatic Swift 6
"""
let system: BedrockRuntimeClientTypes.SystemContentBlock = .text(systemPrompt)

// Create the user message with text prompt and image
let userPrompt = """
Can you review the following Swift code for concurrency issues? Let me know what could go wrong and how to fix it.
"""
let prompt: BedrockRuntimeClientTypes.ContentBlock = .text(userPrompt)

// Create the user message with both text and image content
let userMessage = BedrockRuntimeClientTypes.Message(
    content: [prompt],
    role: .user
)

// Initialize the messages array with the user message
var messages: [BedrockRuntimeClientTypes.Message] = []
messages.append(userMessage)

// Configure the inference parameters
let inferenceConfig: BedrockRuntimeClientTypes.InferenceConfiguration = .init(maxTokens: 4096, temperature: 0.0)

// Create the input for the Converse API with streaming
let input = ConverseStreamInput(inferenceConfig: inferenceConfig, messages: messages, modelId: modelId, system: [system])

// Make the streaming request
do {
    // Process the stream
    let response = try await bedrockClient.converseStream(input: input)

    // Iterate through the stream events
    for try await event in stream {
        switch event {
        case .messagestart:
            print("AI-assistant started to stream"")

        case let .contentblockdelta(deltaEvent):
            // Handle text content as it arrives
            if case let .text(text) = deltaEvent.delta {
                self.streamedResponse + = text
                print(text, termination: "")
            }

        case .messagestop:
            print("\n\nStream ended")
            // Create a complete assistant message from the streamed response
            let assistantMessage = BedrockRuntimeClientTypes.Message(
                content: [.text(self.streamedResponse)],
                role: .assistant
            )
            messages.append(assistantMessage)

        default:
            break
        }
    }
To help you get started, my colleague Dennis maintains a broad range of code examples for multiple use cases and a variety of programming languages.
Available today in Amazon Bedrock This release gives developers immediate access in Amazon Bedrock, a fully managed, serverless service, to the next generation of Claude models developed by Anthropic. Whether you’re already building with Claude in Amazon Bedrock or just getting started, this seamless access makes it faster to experiment, prototype, and scale with cutting-edge foundation models—without managing infrastructure or complex integrations.
Claude Opus 4 is available in the following AWS Regions in North America: US East (Ohio, N. Virginia) and US West (Oregon). Claude Sonnet 4 is available not only in AWS Regions in North America but also in APAC, and Europe: US East (Ohio, N. Virginia), US West (Oregon), Asia Pacific (Hyderabad, Mumbai, Osaka, Seoul, Singapore, Sydney, Tokyo), and Europe (Spain). You can access the two models through cross-Region inference. Cross-Region inference helps to automatically select the optimal AWS Region within your geography to process your inference request.
Opus 4 tackles your most challenging development tasks, while Sonnet 4 excels at routine work with its optimal balance of speed and capability.
If you’re responsible for managing cloud storage across a fast-growing company, you know the drill: more teams, more data, more buckets—and way more complexity. That’s why we’re launching a new enterprise web console, now entering private preview.
Built for scale, security, and simplicity, the new console gives you:
Centralized control over your organization’s cloud storage.
The ability to add multiple admins who each have their own credentials.
More flexibility in bucket creation, including the ability to create buckets in any region.
Built-in zero-trust security features like mandatory MFA and SSO support.
Whether you’re wrangling storage across departments or delivering managed services to clients, this is the command center that helps you move faster, stay secure, and keep everything organized. Because managing cloud storage shouldn’t be harder than using it.
What’s new in the enterprise web console?
The new web console gives IT admins and managed service providers (MSPs) a clean, central hub for managing B2 Cloud Storage deployments—whether you’ve got a few buckets or a few thousand. Here’s what’s under the hood:
Role-based access controls (RBAC): Assign authorized admin users and utilize a resource group architecture so people only access what they need. Great for zero trust—even better for peace of mind.
Mandatory MFA: Because “security optional” isn’t really an option anymore.
SSO and SCIM support: Manage your user base automatically and at scale.
We also revamped the user interface so it’s faster to navigate, easier on the eyes, and just generally gets out of your way.
Storage where you need it
With this update, you’ll be able to create and manage B2 Buckets in any available region. That unlocks a few big wins:
Ensuring data redundancy and disaster recovery through geographically distributed backup copies.
Optimizing application performance for global users by reducing data access latency.
Compliance with data residency rules.
Ready to get started?
We’re rolling out the enterprise console in private preview starting soon. If you’re a Backblaze customer with a committed contract, reach out to your Customer Success Manager to see if you’re eligible. Not sure who your CSM is? Email [email protected] for help.
General availability is coming later this year. Stay tuned—we’ll keep shipping.
I’m pleased to announce developers can now programmatically disable Apple System Integrity Protection (SIP) on their Amazon EC2 Mac instances. System Integrity Protection (SIP), also known as rootless, is a security feature introduced by Apple in OS X El Capitan (2015, version 10.11). It’s designed to protect the system from potentially harmful software by restricting the power of the root user account. SIP is enabled by default on macOS.
SIP safeguards the system by preventing modification of protected files and folders, restricting access to system-owned files and directories, and blocking unauthorized software from selecting a startup disk. The primary goal of SIP is to address the security risk linked to unrestricted root access, which could potentially allow malware to gain full control of a device with just one password or vulnerability. By implementing this protection, Apple aims to ensure a higher level of security for macOS users, especially considering that many users operate on administrative accounts with weak or no passwords.
While SIP provides excellent protection against malware for everyday use, developers might occasionally need to temporarily disable it for development and testing purposes. For instance, when creating a new device driver or system extension, disabling SIP is necessary to install and test the code. Additionally, SIP might block access to certain system settings required for your software to function properly. Temporarily disabling SIP grants you the necessary permissions to fine-tune programs for macOS. However, it’s crucial to remember that this is akin to briefly disabling the vault door for authorized maintenance, not leaving it permanently open.
Disabling SIP on a Mac requires physical access to the machine. You have to restart the machine in recovery mode, then disable SIP with the csrtutil command line tool, then restart the machine again.
Until today, you had to operate with the standard SIP settings on EC2 Mac instances. The physical access requirement and the need to boot in recovery mode made integrating SIP with the Amazon EC2 control plane and EC2 API challenging. But that’s no longer the case! You can now disable and re-enable SIP at will on your Amazon EC2 Mac instances. Let me show you how.
Let’s see how it works Imagine I have an Amazon EC2 Mac instance started. It’s a mac2-m2.metal instance, running on an Apple silicon M2 processor. Disabling or enabling SIP is as straightforward as calling a new EC2 API: CreateMacSystemIntegrityProtectionModificationTask. This API is asynchronous; it starts the process of changing the SIP status on your instance. You can monitor progress using another new EC2 API: DescribeMacModificationTasks. All I need to know is the instance ID of the machine I want to work with.
Prerequisites On Apple silicon based EC2 Mac instances and more recent type of machines, before calling the new EC2 API, I must set the ec2-user user password and enable secure token for that user on macOS. This requires connecting to the machine and typing two commands in the terminal.
# on the target EC2 Mac instance
# Set a password for the ec2-user user
~ % sudo /usr/bin/dscl . -passwd /Users/ec2-user
New Password: (MyNewPassw0rd)

# Enable secure token, with the same password, for the ec2-user
# old password is the one you just set with dscl
~ % sysadminctl -newPassword MyNewPassw0rd -oldPassword MyNewPassw0rd
2025-03-05 13:16:57.261 sysadminctl[3993:3033024] Attempting to change password for ec2-user…
2025-03-05 13:16:58.690 sysadminctl[3993:3033024] SecKeychainCopyLogin returned -25294
2025-03-05 13:16:58.690 sysadminctl[3993:3033024] Failed to update keychain password (-25294)
2025-03-05 13:16:58.690 sysadminctl[3993:3033024] - Done

# The error about the KeyChain is expected. I never connected with the GUI on this machine, so the Login keychain does not exist
# you can ignore this error.  The command below shows the list of keychains active in this session
~ % security list
    "/Library/Keychains/System.keychain"

# Verify that the secure token is ENABLED
~ % sysadminctl -secureTokenStatus ec2-user
2025-03-05 13:18:12.456 sysadminctl[4017:3033614] Secure token is ENABLED for user ec2-user
Change the SIP status I don’t need to connect to the machine to toggle the SIP status. I only need to know its instance ID. I open a terminal on my laptop and use the AWS Command Line Interface (AWS CLI) to retrieve the Amazon EC2 Mac instance ID.
The instance initiates the process and a series of reboots, during which it becomes unreachable. This process can take 60–90 minutes to complete. After that, when I see the status in the console becoming available again, I connect to the machine through SSH or EC2 Instance Connect, as usual.
➜  ~ ssh [email protected]
Warning: Permanently added '54.99.9.99' (ED25519) to the list of known hosts.
Last login: Mon Feb 26 08:52:42 2024 from 1.1.1.1

    ┌───┬──┐   __|  __|_  )
    │ ╷╭╯╷ │   _|  (     /
    │  └╮  │  ___|\___|___|
    │ ╰─┼╯ │  Amazon EC2
    └───┴──┘  macOS Sonoma 14.3.1

➜  ~ uname -a
Darwin Mac-mini.local 23.3.0 Darwin Kernel Version 23.3.0: Wed Dec 20 21:30:27 PST 2023; root:xnu-10002.81.5~7/RELEASE_ARM64_T8103 arm64

➜ ~ csrutil --status
System Integrity Protection status: disabled.
When to disable SIP Disabling SIP should be approached with caution because it opens up the system to potential security risks. However, as I mentioned in the introduction of this post, you might need to disable SIP when developing device drivers or kernel extensions for macOS. Some older applications might also not function correctly when SIP is enabled.
Disabling SIP is also required to turn off Spotlight indexing. Spotlight can help you quickly find apps, documents, emails and other items on your Mac. It’s very convenient on desktop machines, but not so much on a server. When there is no need to index your documents as they change, turning off Spotlight will release some CPU cycles and disk I/O.
Things to know There are a couple of additional things to know about disabling SIP on Amazon EC2 Mac:
On Apple silicon, the setting is volume based. So if you replace the root volume, you need to disable SIP again. On Intel, the setting is Mac host based, so if you replace the root volume, SIP will still be disabled.
After disabling SIP, it will be enabled again if you stop and start the instance. Rebooting an instance doesn’t change its SIP status.
SIP status isn’t transferable between EBS volumes. This means SIP will be disabled again after you restore an instance from an EBS snapshot or if you create an AMI from an instance where SIP is enabled.
(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)
I want to introduce the AWS Cloud Infrastructure Day to provide a comprehensive showcase of latest innovations in AWS cloud infrastructure. This event will highlight cutting-edge advances across compute, artificial intelligence and machine learning (AI/ML), storage solutions, networking capabilities, serverless, and accelerated technologies, and global infrastructure.
Join us for AWS Cloud Infrastructure Day, a free-to-attend one-day virtual event on May 22, 2025, starting at 11:00 AM PDT (2:00 PM EDT). We will stream the event simultaneously across multiple platforms, including LinkedIn Live, Twitter, YouTube, and Twitch.
Here are some of the highlights you can expect from this event:
Willem Visser, VP of EC2 Technology will open with the introduction of the AWS journey since 2006, when Amazon Elastic Compute Cloud (Amazon EC2) was launched with the goal of customer-obsessed innovation. He will speak about the progress made over nearly two decades in cloud infrastructure to support both startups and enterprise workloads based on scale, capacity, and flexibility.
You can learn how AWS developed beyond computing instances to create a complete cloud infrastructure, including the parallel evolution of services like storage and networking capabilities.
Todd Kennedy, Principal Engineer, GoDaddy, will share GoDaddy’s Graviton adoption journey and the benefits it reaped from Graviton. Todd will walk through an example to demonstrate moving Rust workloads to Graviton. Learn how GoDaddy achieved 40 percent compute cost savings and over 20 percent performance gains.
This event covers a variety of topics related to AWS Cloud infrastructure. Here are interesting topics that caught my interest:
Generative AI at the edge – You can learn how to select, fine-tune, and deploy small language models (SLMs) for on-premises and edge use cases due to data residency requirements using AWS hybrid and edge services.
Serverless for agentic AI auditability – You can learn how AWS Step Functions and AWS Lambda transform opaque agentic AI system operations into transparent, auditable workflows.
Accelerated computing – You can get a close look at AWS innovation across silicon, server, and data centers and learn how customers are using AI chips. Learn how you can get started and reduce your generative AI costs.
Networking capability – You can learn how AWS infrastructure—from physical fiber to software-defined networking—enables unparalleled performance and reliability at global scale. The session covers modern application networking patterns while emphasizing secure connectivity solutions for hybrid environments.
This event is perfect for technical decision-makers and developers and offers deep technical insights and hands-on demonstrations of the latest AWS Cloud infrastructure solutions.
(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)
When running container workloads, you need to understand how software vulnerabilities create security risks for your resources. Until now, you could identify vulnerabilities in your Amazon Elastic Container Registry (Amazon ECR) images, but couldn’t determine if these images were active in containers or track their usage. With no visibility if these images were being used on running clusters, you had limited ability to prioritize fixes based on actual deployment and usage patterns.
Starting today, Amazon Inspector offers two new features that enhance vulnerability management, giving you a more comprehensive view of your container images. First, Amazon Inspector now maps Amazon ECR images to running containers, enabling security teams to prioritize vulnerabilities based on containers currently running in your environment. With these new capabilities, you can analyze vulnerabilities in your Amazon ECR images and prioritize findings based on whether they are currently running and when they last ran in your container environment. Additionally, you can see the cluster Amazon Resource Name (ARN), number EKS pods or ECS tasks where an image is deployed, helping you prioritize fixes based on usage and severity.
Second, we’re extending vulnerability scanning support to minimal base images including scratch, distroless, and Chainguard images, and extending support for additional ecosystems including Go toolchain, Oracle JDK & JRE, Amazon Corretto, Apache Tomcat, Apache httpd, WordPress (core, themes, plugins), and Puppeteer, helping teams maintain robust security even in highly optimized container environments.
Through continual monitoring and tracking of images running on containers, Amazon Inspector helps teams identify which container images are actively running in their environment and where they’re deployed, detecting Amazon ECR images running on containers in Amazon Elastic Container Service (Amazon ECS) and Amazon Elastic Kubernetes Service (Amazon EKS), and any associated vulnerabilities. This solution supports teams managing Amazon ECR images across single AWS accounts, cross-account scenarios, and AWS Organizations with delegated administrator capabilities, enabling centralized vulnerability management based on container images running patterns.
In the Amazon Inspector console, I navigate to General settings and select ECR scanning settings from the navigation panel. Here, I can configure the new Image re-scan mode settings by choosing between Last in-use date and Last pull date. I leave it as it is by default with Last in-usedate and set the Image last in use date to 14 days. These settings make it so that Inspector monitors my images based on when they were running in the last 14 days in my Amazon ECS or Amazon EKS environments. After applying these settings, Amazon Inspector starts tracking information about images running on containers and incorporating it into vulnerability findings, helping me focus on images actively running in containers in my environment.
After it’s configured, I can view information about images running on containers in the Details menu, where I can see last in-use and pull dates, along with EKS pods or ECS tasks count.
When selecting the number of Deployed ECS Tasks/EKS Pods, I can see the cluster ARN, last use dates, and Type for each image.
For cross-account visibility demonstration, I have a repository with EKS pods deployed in two accounts. In the Resources coverage menu, I navigate to Container repositories, select my repository name and choose the Image tag. As before, I can see the number of deployed EKS pods/ECS tasks.
When I select the number of deployed EKS pods/ECS tasks, I can see that it is running in a different account.
In the Findings menu, I can review any vulnerabilities, and by selecting one, I can find the Last in use date and Deployed ECS Tasks/EKS Pods involved in the vulnerability under Resource affected data, helping me prioritize remediation based on actual usage.
In the All Findings menu, you can now search for vulnerabilities within account management, using filters such as Account ID, Image in use count and Image last in use at.
Key features and considerations Monitoring based on container image lifecycle – Amazon Inspector now determines image activity based on: image push date ranging duration 14, 30, 60, 90, or 180 days or lifetime, image pull date from 14, 30, 60, 90, or 180 days, stopped duration from never to 14, 30, 60, 90, or 180 days and status of image running on the container. This flexibility lets organizations tailor their monitoring strategy based on actual container image usage rather than only repository events. For Amazon EKS and Amazon ECS workloads, last in use, push and pull duration are set to 14 days, which is now the default for new customers.
Image runtime-aware finding details – To help prioritize remediation efforts, each finding in Amazon Inspector now includes the lastInUseAt date and InUseCount, indicating when an image was last running on the containers and the number of deployed EKS pods/ ECS tasks currently using it. Amazon Inspector monitors both Amazon ECR last pull date data and images running on Amazon ECS tasks or Amazon EKS pods container data for all accounts, updating this information at least once daily. Amazon Inspector integrates these details into all findings reports and seamlessly works with Amazon EventBridge. You can filter findings based on the lastInUseAt field using rolling window or fixed range options, and you can filter images based on their last running date within the last 14, 30, 60, or 90 days.
Comprehensive security coverage – Amazon Inspector now provides unified vulnerability assessments for both traditional Linux distributions and minimal base images including scratch, distroless, and Chainguard images through a single service. This extended coverage eliminates the need for multiple scanning solutions while maintaining robust security practices across your entire container ecosystem, from traditional distributions to highly optimized container environments. The service streamlines security operations by providing comprehensive vulnerability management through a centralized platform, enabling efficient assessment of all container types.
Enhanced cross-account visibility – Security management across single accounts, cross-account setups, and AWS Organizations is now supported through delegated administrator capabilities. Amazon Inspector shares images running on container information within the same organization, which is particularly valuable for accounts maintaining golden image repositories. Amazon Inspector provides all ARNs for Amazon EKS and Amazon ECS clusters where images are running, if the resource belongs to the account with an API, providing comprehensive visibility across multiple AWS accounts. The system updates deployed EKS pods or ECS tasks information at least one time daily and automatically maintains accuracy as accounts join or leave the organization.
PS: Writing a blog post at AWS is always a team effort, even when you see only one name under the post title. In this case, I want to thank Nirali Desai, for her generous help with technical guidance, and expertise, which made this overview possible and comprehensive.
(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)
Amazon EC2 P6-B200 instances accelerate a broad range of GPU-enabled workloads but are especially well-suited for large-scale distributed AI training and inferencing for foundation models (FMs) with reinforcement learning (RL) and distillation, multimodal training and inference, and HPC applications such as climate modeling, drug discovery, seismic analysis, and insurance risk modeling.
When combined with Elastic Fabric Adapter (EFAv4) networking, hyperscale clustering by EC2 UltraClusters, and advanced virtualization and security capabilities by AWS Nitro System, you can train and serve FMs with increased speed, scale, and security. These instances also deliver up to two times the performance for AI training (time to train) and inference (tokens/sec) compared to EC2 P5en instances.
You can accelerate time-to-market for training FMs and deliver faster inference throughput, which lowers inference cost and helps increase adoption of generative AI applications as well as increased processing performance for HPC applications.
EC2 P6-B200 instances specifications New EC2 P6-B200 instances provide eight NVIDIA B200 GPUs with 1440 GB of high bandwidth GPU memory, 5th Generation Intel Xeon Scalable processors (Emerald Rapids), 2 TiB of system memory, and 30 TB of local NVMe storage.
Here are the specs for EC2 P6-B200 instances:
Instance size
GPUs (NVIDIA B200)
GPU memory (GB)
vCPUs
GPU Peer to peer (GB/s)
Instance storage (TB)
Network bandwidth (Gbps)
EBS bandwidth (Gbps)
P6-b200.48xlarge
8
1440 HBM3e
192
1800
8 x 3.84 NVMe SSD
8 x 400
100
These instances feature up to 125 percent improvement in GPU TFLOPs, 27 percent increase in GPU memory size, and 60 percent increase in GPU memory bandwidth compared to P5en instances.
P6-B200 instances in action You can use P6-B200 instances in the US West (Oregon) AWS Region through EC2 Capacity Blocks for ML. To reserve your EC2 Capacity Blocks, choose Capacity Reservations on the Amazon EC2 console.
Select Purchase Capacity Blocks for ML and then choose your total capacity and specify how long you need the EC2 Capacity Block for p6-b200.48xlarge instances. The total number of days that you can reserve EC2 Capacity Blocks is 1-14 days, 21 days, 28 days, or multiples of 7 up to 182 days. You can choose your earliest start date for up to 8 weeks in advance.
Now, your EC2 Capacity Block will be scheduled successfully. The total price of an EC2 Capacity Block is charged up front, and the price doesn’t change after purchase. The payment will be billed to your account within 12 hours after you purchase the EC2 Capacity Blocks. To learn more, visit Capacity Blocks for ML in the Amazon EC2 User Guide.
When launching P6-B200 instances, you can use AWS Deep Learning AMIs (DLAMI) to support EC2 P6-B200 instances. DLAMI provides ML practitioners and researchers with the infrastructure and tools to quickly build scalable, secure, distributed ML applications in preconfigured environments.
(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)
Starting today, you can use AWS CodeBuild Docker Server capability to provision a dedicated and persistent Docker server directly within your CodeBuild project. With Docker Server capability, you can accelerate your Docker image builds by centralizing image building to a remote host, which reduces wait times and increases overall efficiency.
From my benchmark, with this Docker Server capability, I reduced the total building time by 98 percent, from 24 minutes and 54 seconds to 16 seconds. Here’s a quick look at this feature from my AWS CodeBuild projects.
AWS CodeBuild is a fully managed continuous integration service that compiles source code, runs tests, and produces software packages ready for deployment. Building Docker images is one of the most common use cases for CodeBuild customers, and the service has progressively improved this experience over time by releasing features such as Docker layer caching and reserved capacity features to improve Docker build performance.
With the new Docker Server capability, you can reduce build time for your applications by providing a persistent Docker server with consistent caching. When enabled in a CodeBuild project, a dedicated Docker server is provisioned with persistent storage that maintains your Docker layer cache. This server can handle multiple concurrent Docker build operations, with all builds benefiting from the same centralized cache.
Using AWS CodeBuild Docker Server Let me walk you through a demonstration that showcases the benefits with the new Docker Server capability.
For this demonstration, I’m building a complex, multi-layered Docker image based on the official AWS CodeBuild curated Docker images repository, specifically the Dockerfile for building a standard Ubuntu image. This image contains numerous dependencies and tools required for modern continuous integration and continuous delivery (CI/CD) pipelines, making it a good example of the type of large Docker builds that development teams regularly perform.
# Copyright 2020-2024 Amazon.com, Inc. or its affiliates. All Rights Reserved.
#
# Licensed under the Amazon Software License (the "License"). You may not use this file except in compliance with the License.
# A copy of the License is located at
#
#    http://aws.amazon.com/asl/
#
# or in the "license" file accompanying this file.
# This file is distributed on an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, express or implied.
# See the License for the specific language governing permissions and limitations under the License.
FROM public.ecr.aws/ubuntu/ubuntu:20.04 AS core

ARG DEBIAN_FRONTEND="noninteractive"

# Install git, SSH, Git, Firefox, GeckoDriver, Chrome, ChromeDriver,  stunnel, AWS Tools, configure SSM, AWS CLI v2, env tools for runtimes: Dotnet, NodeJS, Ruby, Python, PHP, Java, Go, .NET, Powershell Core,  Docker, Composer, and other utilities
COMMAND REDACTED FOR BREVITY
# Activate runtime versions specific to image version.
RUN n $NODE_14_VERSION
RUN pyenv  global $PYTHON_39_VERSION
RUN phpenv global $PHP_80_VERSION
RUN rbenv  global $RUBY_27_VERSION
RUN goenv global  $GOLANG_15_VERSION

# Configure SSH
COPY ssh_config /root/.ssh/config
COPY runtimes.yml /codebuild/image/config/runtimes.yml
COPY dockerd-entrypoint.sh /usr/local/bin/dockerd-entrypoint.sh
COPY legal/bill_of_material.txt /usr/share/doc/bill_of_material.txt
COPY amazon-ssm-agent.json /etc/amazon/ssm/amazon-ssm-agent.json

ENTRYPOINT ["/usr/local/bin/dockerd-entrypoint.sh"]
This Dockerfile creates a comprehensive build environment with multiple programming languages, build tools, and dependencies – exactly the type of image that would benefit from persistent caching.
In the build specification (buildspec), I use the docker buildx build . command:
To enable the Docker Server capability, I navigate to the AWS CodeBuild console and select Create project. I can also enable this capability when editing existing CodeBuild projects.
I fill in all details and configuration. In the Environment section, I select Additional configuration.
Then, I scroll down and find Docker server configuration and select Enable docker server for this project. When I select this option, I can choose a compute type configuration for the Docker server. When I’m finished with the configurations, I create this project.
Now, let’s see the Docker Server capability in action.
The initial build takes approximately 24 minutes and 54 seconds to complete because it needs to download and compile all dependencies from scratch. This is expected for the first build of such a complex image.
For subsequent builds with no code changes, the build takes only 16 seconds and that shows 98% reduction in build time.
Looking at the logs, I can see that with Docker Server, most layers are pulled from the persistent cache:
The persistent caching provided by the Docker Server maintains all layers between builds, which is particularly valuable for large, complex Docker images with many layers. This demonstrates how Docker Server can dramatically improve throughput for teams running numerous Docker builds in their CI/CD pipelines.
Additional things to know Here are a couple of things to note:
Architecture support – The feature is available for both x86 (Linux) and ARM builds.
Pricing – To learn more about pricing for Docker Server capability, refer to the AWS CodeBuild pricing page.
Availability – This feature is available in all AWS Regions where AWS CodeBuild is offered. For more information about the AWS Regions where CodeBuild is available, see the AWS Regions page.
(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)
Generative AI has brought many new possibilities to organizations. It has equipped them with new abilities to retire technical debt, modernize legacy systems, and build agile infrastructure to help unlock the value that is trapped in their internal data. However, many enterprises still rely heavily on legacy IT infrastructure, particularly mainframes and VMware-based systems. These platforms have been the backbone of critical operations for decades, but they hinder organizations’ ability to innovate, scale effectively, and reduce technical debt in an era where cloud-first strategies dominate. The need to modernize these workloads is clear, but the journey has traditionally been complex and risky.
The complexity spans multiple dimensions. Financially, organizations face mounting licensing costs and expensive migration projects. Technically, they must untangle legacy dependencies while meeting compliance requirements. Organizationally, they must manage the transition of teams who’ve built careers around legacy systems and navigate undocumented institutional knowledge.
AWS Transform directly addresses these challenges with purpose-built agentic AI that accelerates and de-risks your legacy modernization. It automates the assessment, planning, and transformation of both mainframe and VMware workloads into cloud based architectures, streamlining the entire process. Through intelligent insights, automated code transformation, and human-in-the-loop workflows, organizations can now tackle even the most challenging modernization projects with greater confidence and efficiency.
Mainframe workload migration AWS Transform for mainframe is the first agentic AI service for modernizing mainframe workloads at scale. The specialized mainframe agent accelerates mainframe modernization by automating complex, resource-intensive tasks across every phase of modernization — from initial assessment to final deployment. It streamlines the migration of legacy applications built on IBM z/OS Db2, including COBOL, CICS, DB2, and VSAM, to modern cloud environments–cutting modernization timelines from years to months.
Let’s look at a few examples of how AWS Transform can help you through different aspects of the migration process.
Code analysis – AWS Transform provides comprehensive insights into your codebase, automatically examining mainframe codebases, creating detailed dependency graphs, measuring code complexity, and identifying component relationships
Documentation – AWS Transform for mainframe creates comprehensive technical and functional documentation of mainframe applications, preserving critical knowledge about features, program logic, and data flows. You can interact with the generated documentation through an AI-powered chat interface to discover and retrieve information quickly.
Business rule extraction – AWS Transform extracts and presents complex logic in plain language so you can gain visibility into business processes embedded within legacy applications. This enables both business and technical stakeholders to gain a greater understanding of application functionality.
Code decomposition – AWS Transform offers sophisticated code decomposition tools, including interactive dependency graphs and domain separation capabilities, enabling users to visualize and modify relationships between components while identifying key business functions. The solution also streamlines migration planning through an interactive wave sequence planner that considers user preferences to generate optimized migration strategies.
Modernization Wave Planning – With its specialized agent, AWS Transform for mainframe creates prioritized modernization wave sequences based on code and data dependencies, code volume, and business priorities. It enables modernization teams to make data-driven, customized migration plans that align to their specific organizational needs.
Code refactoring – AWS Transform can refactor millions of lines of mainframe code in minutes, converting COBOL, VSAM, and DB2 systems into modern Java Spring Boot applications while maintaining functional equivalence and transforming CICS transactions into web services and JCL batch processes into Groovy scripts. The solution provides high-quality output through configurable settings and bundled runtime capabilities, producing Java code that emphasizes readability, maintainability, and technical excellence.
Deployments – AWS Transform provides customizable deployment templates that streamline the deployment process through user-defined inputs. For added efficiency, the solution bundles the selected runtime version with the migrated application, enabling seamless deployment as a complete package.
By integrating intelligent documentation analysis, business rules extraction, and human-in-the-loop collaboration capabilities, AWS Transform helps organizations accelerate their mainframe transformation while reducing risk and maintaining business continuity.
VMware modernization With rapid changes in VMware licensing and support model, organizations are increasingly exploring alternatives despite the difficulties associated with migrating and modernizing VMware workloads. This is aggravated by the fact that the accumulation of technical debt typically creates complex, poorly documented environments managed by multiple teams, leading to vendor lock-in and collaboration challenges that hinder migration efforts further.
AWS Transform is the first agentic AI service for VMware modernization of its kind that helps you to overcome those difficulties. It can offset risk and accelerate the modernization of VMware workloads by automating application discovery, dependency mapping, migration planning, network conversion, and EC2 instance optimization, reducing manual effort and accelerating cloud adoption.
The process is organized into four phases: inventory discovery, wave planning, network conversion, and server migration. It uses agentic AI capabilities to analyze and map complex VMware environments, converting network configurations into AWS built-in constructs and helps you to orchestrate dependency-aware migration waves for seamless cutovers. In addition, it also provides a collaborative web interface that keeps AWS teams, partners, and customers aligned throughout the modernization journey.
Let’s take a quick tour to see how this works.
Setting up Before you can start using the service, you must first enable it by navigating to the AWS Transform console. AWS Transform requires AWS IAM Identity Center (IdC) to manage users and setup appropriate permissions. If you don’t yet have IdC set up it will ask you to configure it first and return to the AWS Transform console later to continue the process.
With IdC available, you can then proceed to choosing the encryption settings. AWS Transform gives you the option to use a default AWS managed key or you can use your own custom keys through AWS Key Management Service (AWS KMS).
After completing this step, AWS Transform will be enabled. You can manage admin access to the console by navigating to Users and using the search box to find them. You must create users or groups in IdC first if they don’t already exist. The service console will help admins provision users who will get access to the web app. Each provisioned user receives an email with a link to set password and get their personalized URL for the webapp.
You interact with AWS Transform through a dedicated web experience. To get the url, navigate to Settings where you can check your configurations and copy the links to the AWS Transform web experience where you and your teams can start using the service.
Discovery AWS Transform can discover your VMware environment either automatically through AWS Application Discovery Service collectors or you can provide your own data by importing existing RVTools export files.
To get started, choose the Create or select connectors task and provide the account IDs for one or more AWS accounts that will be used for discovery. This will generate links that you can follow to authorize each account for usage within AWS Transform. You can then move on to the Perform discovery task, where you can choose to install AWS Application Discovery Service collectors or upload your own files such as exports from RVTools.
Provisioning The steps for the provisioning phase are similar to the ones described earlier for discovery. You connect target AWS accounts by entering their account IDs and validating the authorization requests which will then enable the next steps such as the Generate VPC configuration step. Here, you can import your RVTools files or NSX exports from Import/Export from NSX, if applicable, and enable AWS Transform to understand your networking requirements.
Review the proposed changes and, if you’re happy, start the deployment process of the AWS resources to the target accounts.
Deployment AWS Transform requires you to set up AWS Application Migration Service (MGN) in the target AWS accounts to automate the migration process. Choose the Initiate VM migration task and use the link to navigate to the service console, then follow the instructions to configure it.
After setting up service permissions, you’ll proceed to the implementation phase of the waves created by AWS Transform and start the migration process. For each wave, you’ll first be asked to make various choices such as setting the sizing preference and tenancy for the Amazon Elastic Compute Cloud (Amazon EC2) instances. Confirm your selections and continue following the instructions given by AWS Transform until you reach the Deploy replication agents stage, where you can start the migration for that wave.
After you start the waves migration process, you can switch to the dashboard at any time to check on progress.
With its agentic AI capabilities, AWS Transform offers a powerful solution for accelerating and de-risking mainframe and VMware modernization workloads. By automating complex assessment and transformation processes, AWS Transform reduces the time associated with legacy system migration while minimizing the potential for errors and business disruption enabling more agile, efficient, and future-ready IT environments within your organization.
Things to know Availability – AWS Transform for mainframe is available in US East (N. Virginia) and Europe (Frankfurt) Regions. AWS Transform for VMware offers different availability options for data collection and migrations. Please refer to the AWS Transform for VMware FAQ for more details.
Pricing – Currently, we offer our core features—including assessment and transformation—at no cost to AWS customers.
(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)
Welcome to the first Drive Stats of 2025. In case you missed it, the 2024 Drive Stats report was the last for long-time Drive Stats guru, Andy Klein, who is happily retired—off putting the “green” in greener pastures by working on his golf game. We–being Backblaze staff writer Stephanie Doyle and Chief Technical Evangelist Pat Patterson–are picking up where Andy left off, bringing you the metrics and analysis you know and love. Now, on to the numbers!
As of March 31, 2025, we had 312,831 drives under management. Of that total, there were 3,970 boot drives and 308,861 data drives. We’ll review their annualized failure rates (AFRs) as of Q1 2025, and we’ll dig into the average age of drive failure by model, drive size, and more. Along the way, we’ll share our observations and insights on the data presented and, this time around, we’ve got some exciting updates to share about how we produce Drive Stats. (Stay tuned, fellow Snowflake fans.)
As always, we look forward to your thoughts—we’ll see you in the comments section.
Sign up for the Drive Stats LinkedIn Live
Ready to dive deeper into the data? Tune in Thursday, May 15, 2025 at 10:00 a.m. PT, to query the new Drive Stats team, Stephanie Doyle and Pat Patterson. Feel free to drop us a line with any questions you want us to answer.
Q1 2025 hard drive failure rates
As mentioned above, at the end of Q1 2025, we were running 312,831 drives. During the quarter as a whole, however, we were monitoring a total of 318,426 drives; this count includes those that were taken out of service during the quarter, either because they failed or were only used temporarily.
We’ll discuss the criteria we used in the next section of this report. Removing these drives leaves us with 317,833 hard drives to analyze. The table below shows the annualized failure rates (AFR) for Q1 2025 for this collection of drives.
Backblaze Hard Drive Failure Rates for Q1 2025
Reporting period January 1, 2025–March 31, 2025 inclusive Drive models with drive count > 100 as of March 31, 2025 and drive days > 10,000 in Q1 2025.
Notes and observations
The 4TB drives are hanging on and finishing strong. Good news: We have another quarter’s worth of data on our beloved 4TB drives (though the planned migration is well underway). True to their history, the 4TB drives showed wonderfully low failure rates, with yet another quarter of zero failures from model HMS5C4040ALE640 and 0.34% AFR from model HMS5C4040BLE640.
Keeping an eye on the 20TB+ pool. The 24TB Seagate (model ST24000NM002H) no longer has a perfect record, with eight failures for the quarter. Still, the drives put up a respectable 1.00% AFR. Meanwhile, the 20TB+ drives as a pool are averaging a 0.72% AFR, coming in lower than the overall failure rates—always a promising sign.
Zero failures for the quarter. Four drives get a gold star for zero failures this quarter:
The 4TB HGST (model HMS5C4040ALE640)
The Seagate 8TB (model ST8000NM000A)
Seagate 12TB (model ST12000NM000J)
Seagate 14TB (model ST14000NM000J)
Three out of the four also had zero failures last quarter, all but the Seagate 12TB.
The quarterly failure rate is slightly higher. The quarterly failure rate went up from 1.35% to 1.42%. As with the zero-failure club, our higher-end outlier AFRs show some of the usual suspects:
We noted earlier we removed 593 drives from consideration when we produced the table above covering Q4 2024. There are two primary reasons we did not consider these drive models.
Testing. These are drives of a given model that we monitor and collect Drive Stats data on, but are not considered production drives at this time. For example, drives undergoing certification testing to determine if they are performant enough for our environment are not included in our Drive Stats calculations.
Insufficient data points. When we calculate the annualized failure rate for a drive model for a given period of time (quarterly, annual, or lifetime), we want to ensure we have enough data to reliably do so. Therefore we have defined criteria for a drive model to be included in the tables and charts for the specified period of time. Models that do not meet these criteria are not included in the tables and charts for the period in question.
Regardless of whether or not a given drive model is included in the charts and tables, all of the data for all of the drives we use is included in our Drive Stats dataset which you can download by visiting our Drive Stats page.
As with the Q4 quarterly results, we will apply these criteria to the annual and lifetime charts that follow in this report.
Lifetime hard drive failure rates
As of the end of Q1 2025, we were tracking 312,831 data hard drives. To be considered for the lifetime review, a drive model was required to have 500 or more drives as of the end of Q1 2025 and have over 100,000 accumulated drive days during their lifetime. When we removed those drive models which did not meet the lifetime criteria, we had 312,493 drives grouped into 26 models remaining for analysis as shown in the table below.
Backblaze Lifetime Hard Drive Failure Rates
Reporting period ending March 31, 2025 inclusive Drive models with > 500 drives and > 100,000 lifetime drive days
Notes and observations
The lifetime AFR remains steady, despite some drives having significant change. We see virtually no change in our overall lifetime AFR, which we last tracked at 1.31% in the 2024 Year-End Drive Stats Report. But, with some drive models showing significant change in year-over-year AFR, it’s worth digging in a little deeper.
Statistically significant improved AFRs:
Both the 12TB and the 14TB had the same number of failures (or nearly so). Meanwhile, the Toshiba 20TB and WDC 22TB had more failures, but added a significant number of drives to the fleet. Both of these activities increase the number of drive days we tracked for the model’s drive pool, so these results are unsurprising.
Statistically significant worsened AFRs:
Meanwhile, we have a few things happening for the significantly worsened AFRs. The WDC drive models are all top performers from a failure perspective, even a change from .45 to .48 shows up in the numbers.
That leaves us with two HGST 12TB drives. Both come in above the average failure rate, at 1.45% (model: HUH721212ALE604) and 2.06% (model: HUH721212ALN604). We can give HUH721212ALE604 a pass—with the drive pool showing an average age of 67.1 months, or about five and a half years, it’s firmly on track with the expected pattern defined by the bathtub curve.
Where does that leave us with model HUH721212ALE604? We’ll keep an eye on it. Given that its AFR rate isn’t too far off from the total AFR of the Backblaze drive fleet, it’s not hugely concerning unless we see the rate of change continue.
What’s new with Drive Stats?
In taking on this report, our main focus was to ensure continuity with our decades-old dataset. That said, we also saw some opportunities to streamline the process of data collection, a continuation of the work that David Winings talked about in Overload to Overhaul: How We Upgraded the Drive Stats Data and Drive Stats Data Deep Dive: The Architecture. All of these things set us up for not just an easier time generating this report, but some bigger plans in the future. (We won’t tip our hand yet—but stay tuned.)
Drive Stats gets a Snowflake upgrade
When we first started tracking Drive Stats way back in 2013, data collection was very ad hoc. For the first few years, when Brian Beach was at the helm, we published stats once a year. When Andy took over in 2015, he moved to publishing quarterly data (starting in 2016). As the dataset grew, and Andy’s collection of lightweight desktop apps started to run out of steam, it became apparent that we needed to upgrade to more capable analytical tooling. For a variety of operational reasons, Andy was gamely running SQL queries against CSV data imported into a MySQL instance running on his laptop—and having to do a ton of manual data cleanup to boot. (Pun obviously intended.)
This year, with the help of our colleagues on the database engineering team (shoutout to Tom Roden—thanks so much!), we were able to get the Drive Stats data included in the Backblaze Snowflake instance. Gone are the days of us bugging folks for exports that take hours to process! We can run lightweight queries against a cached, structured table.
We started from Andy’s SQL queries and tweaked them a bit to match the logic and nomenclature of Snowflake fields. Once we had that worked out, the first thing we did was validate our methodology by running the Q4 Drive Stats numbers and comparing them to Andy’s—success.
It helps that Pat has experimented with our Drive Stats dataset in Trino and other analytical tools like Apache Iceberg, so it’s certainly not the first time he’s considered methodology and tooling for this problem. Going forward, we may further refine the process, but for now, the migration to Snowflake saved us a ton of time and manual data cleanup.
The Hard Drive Stats data
The complete dataset used to create the tables and charts in this report is available on our Hard Drive Test Data page. You can download and use this data for free for your own purpose. All we ask are three things: 1) you cite Backblaze as the source if you use the data, 2) you accept that you are solely responsible for how you use the data, and 3) you do not sell this data itself to anyone; it is free.
Good luck, and let us know if you find anything interesting.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.


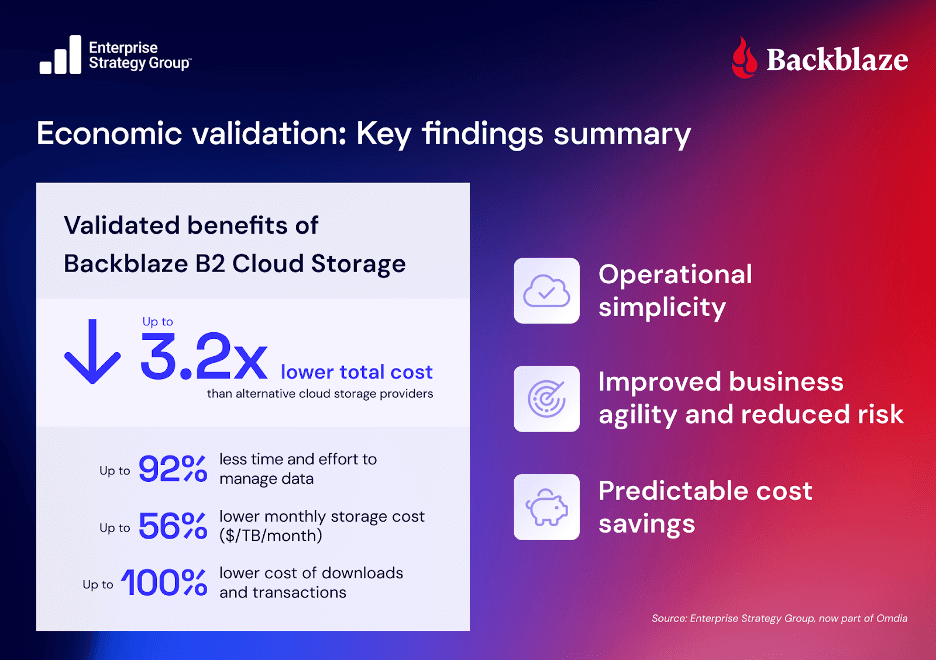
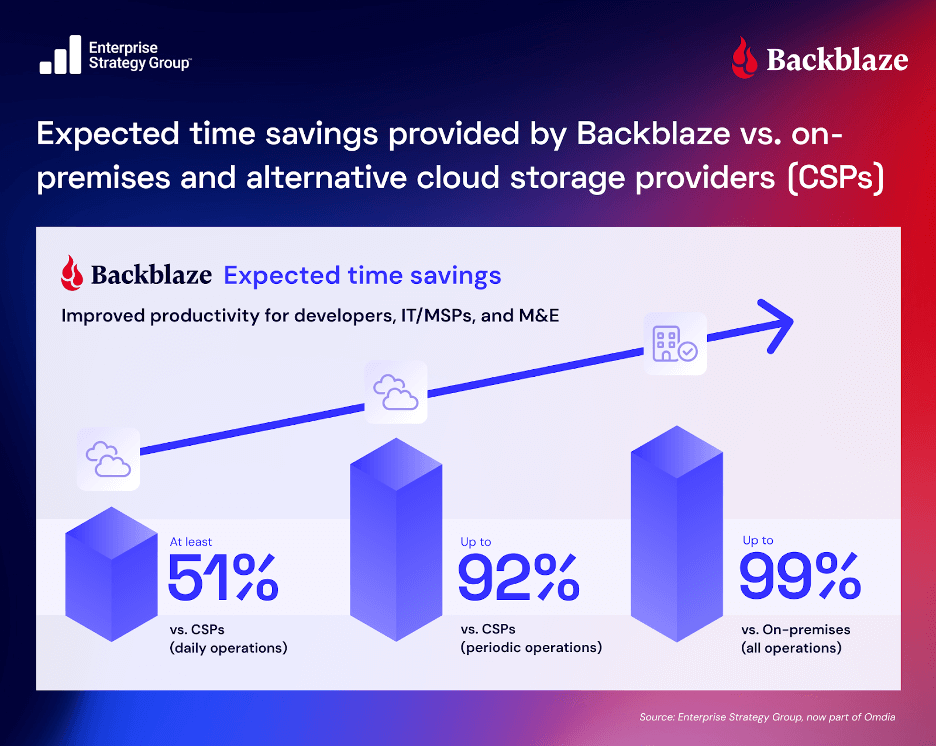




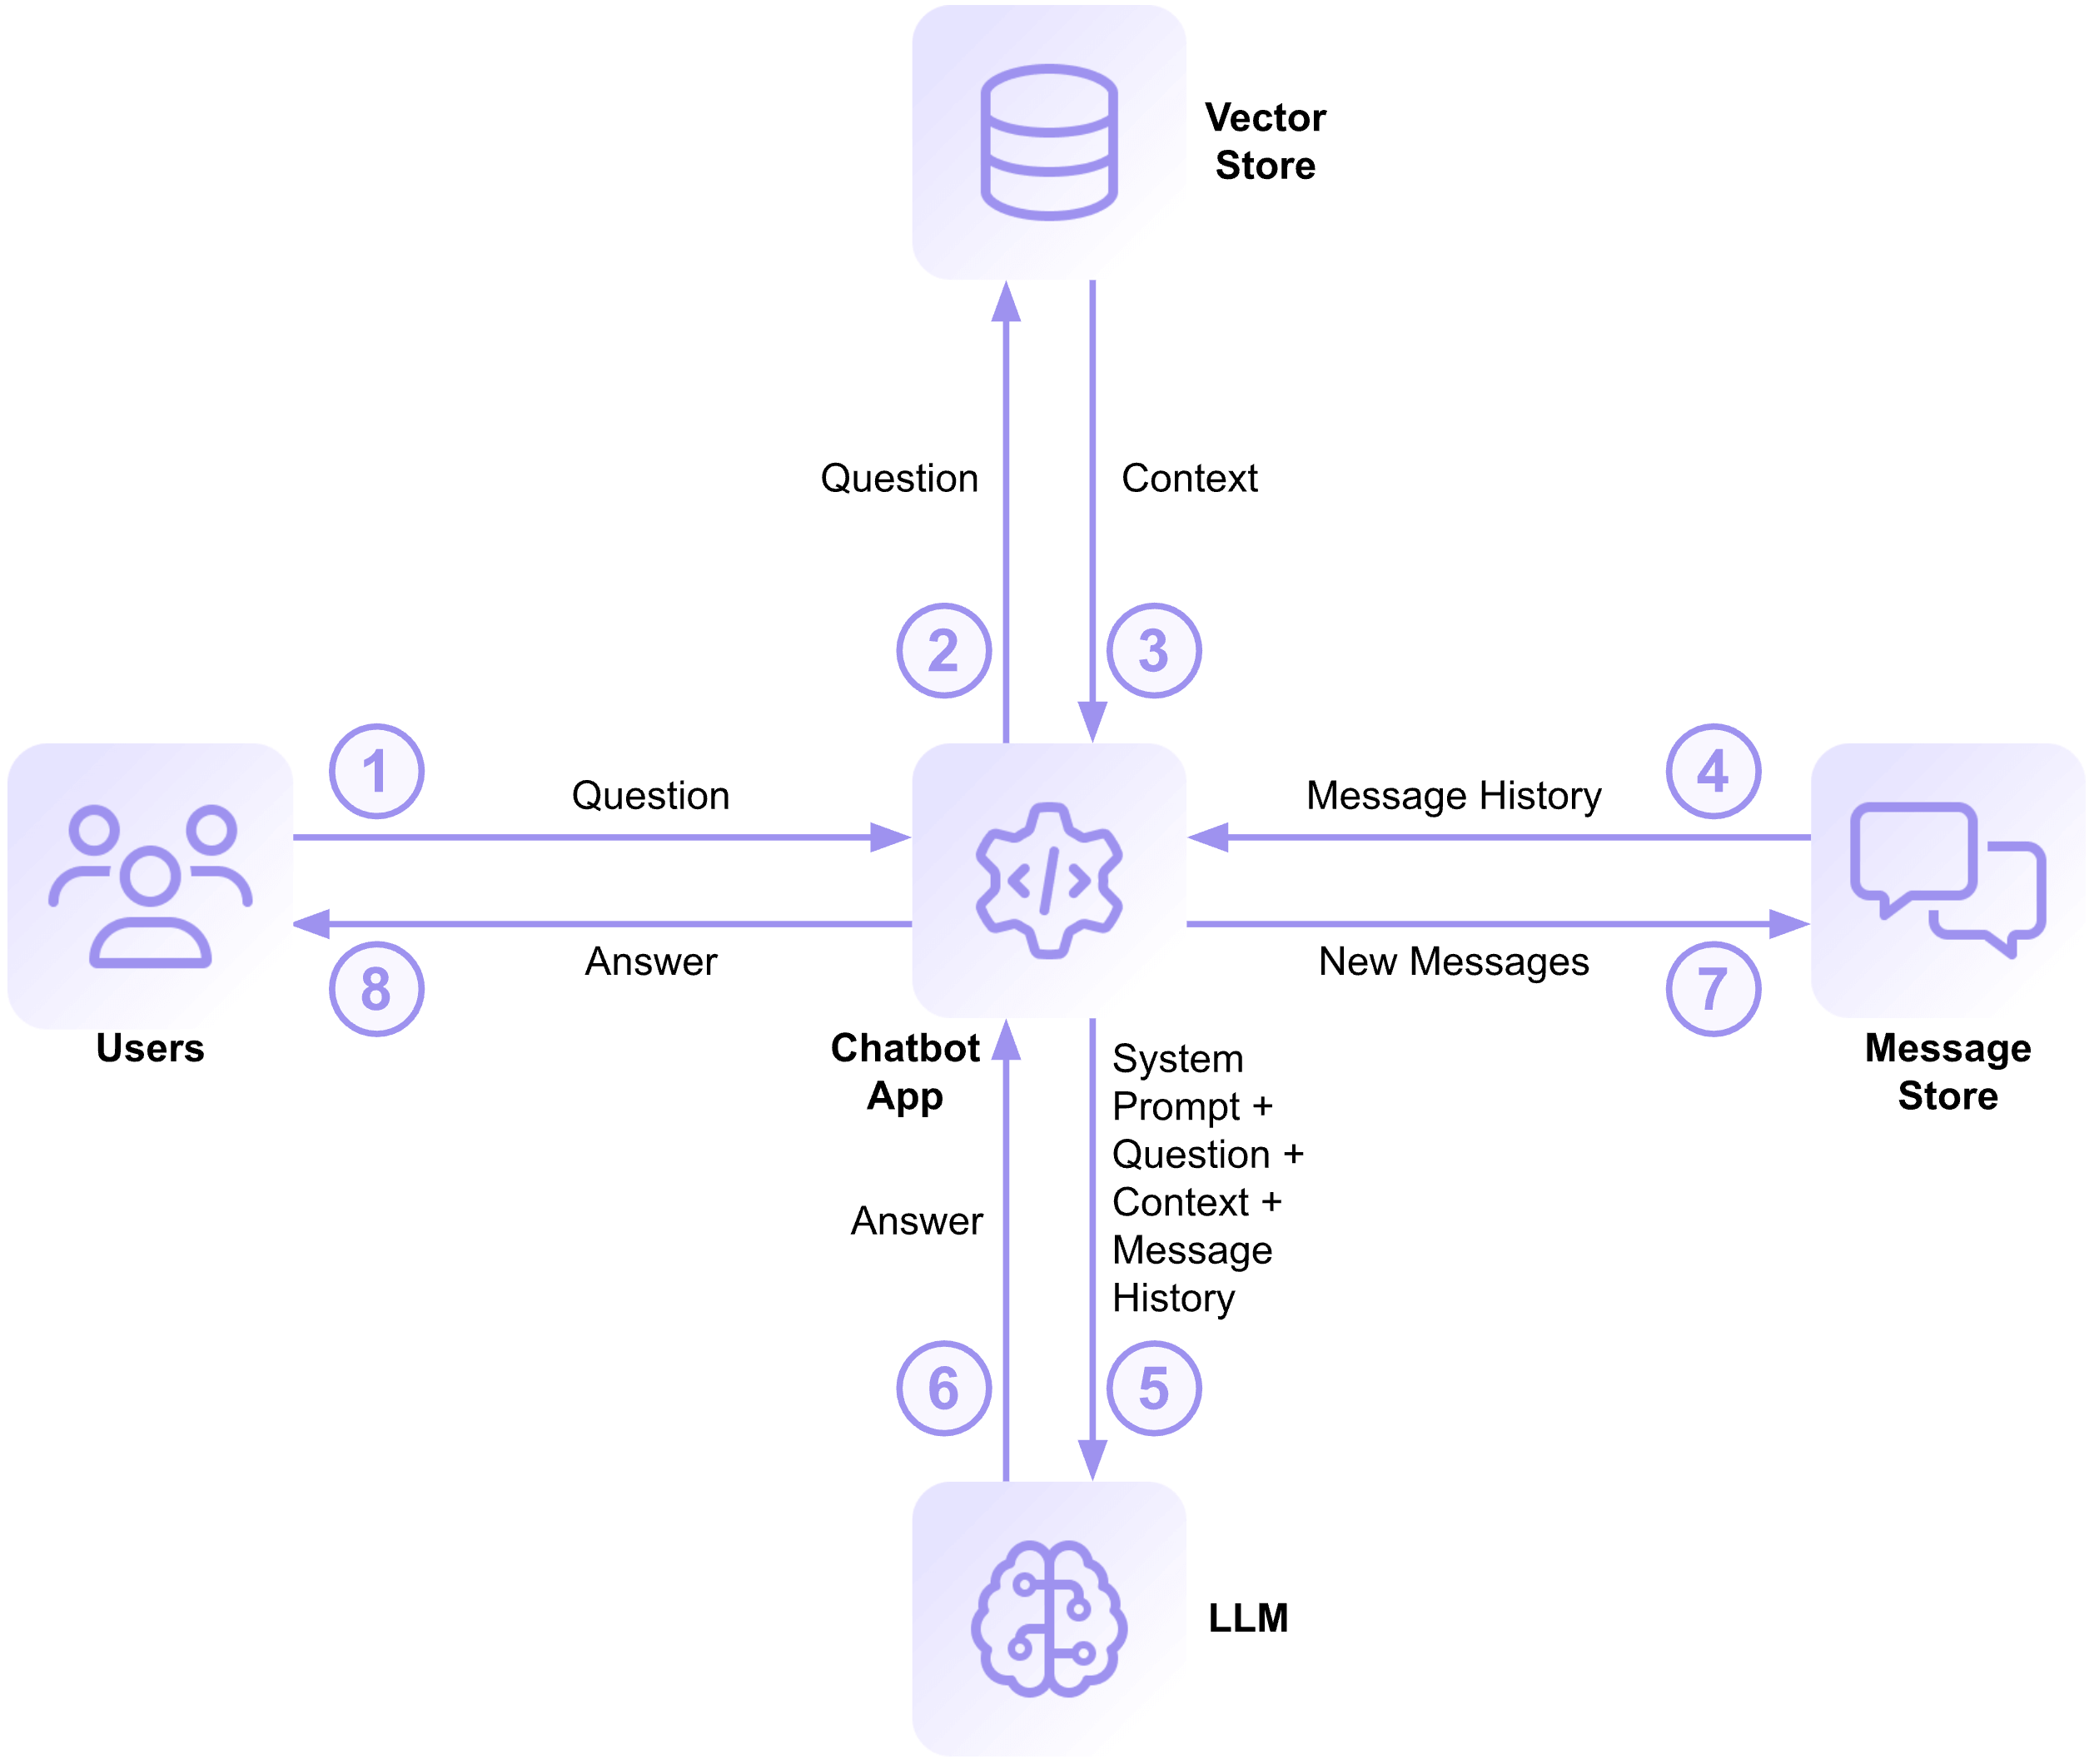
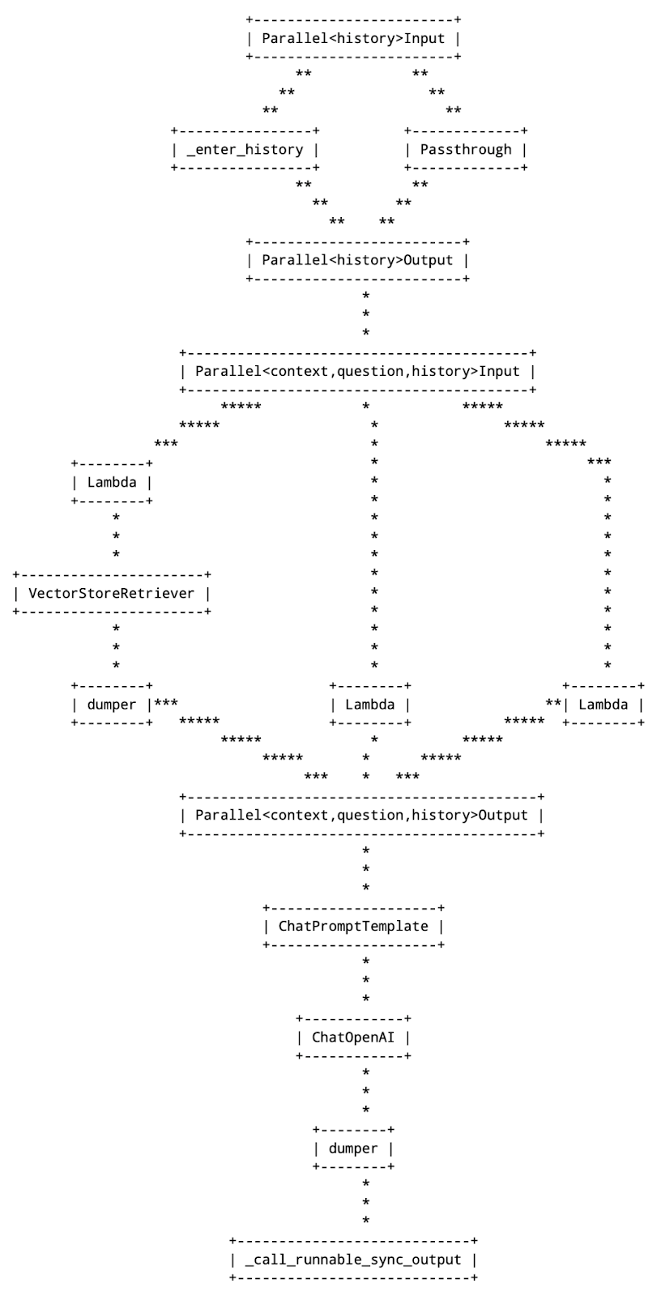

 Willem Visser, VP of EC2 Technology will open with the introduction of the AWS journey since 2006, when
 Todd Kennedy, Principal Engineer, GoDaddy, will share GoDaddy’s Graviton adoption journey and the benefits it reaped from Graviton. Todd will walk through an example to demonstrate moving Rust workloads to Graviton. Learn how GoDaddy achieved 40 percent compute cost savings and over 20 percent performance gains.