Tag Archives: Compute

New – Amazon EC2 R7iz Instances Memory-Optimized for High CPU Performance, Memory-Intensive Workloads

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/new-amazon-ec2-r7iz-instances-memory-optimized-for-high-cpu-performance-memory-intensive-workloads/

Today we’re announcing general availability of the Amazon EC2 R7iz instances. R7iz instances are the fastest 4th Generation Intel Xeon Scalable-based (Sapphire Rapids) instances in the cloud with 3.9 GHz sustained all-core turbo frequency. R7iz instances are suitable for workloads where there’s a requirement for more memory to process additional data, larger sizes of instances to scale up, higher compute and memory performance to reduce completion times, and higher networking and Amazon Elastic Block Store (Amazon EBS) performance to improve latency. The high compute performance of the R7iz instances, combined with a large amount of memory, results in increased overall performance for applications that include front-end electronic design automation (EDA), relational database workloads with high per core licensing fees, and financial, actuarial, and data analytics simulation workloads. This can help you speed time to market for product development while reducing licensing costs.

R7iz Instances

The specs for the R7iz instances are as follows.

vCPUs
Memory (GiB)
Network Bandwidth
EBS Bandwidth
r7iz.large 2 16 Up to 12.5 Gbps Up to 10 Gbps
r7iz.xlarge 4 32 Up to 12.5 Gbps Up to 10 Gbps
r7iz.2xlarge 8 64 Up to 12.5 Gbps Up to 10 Gbps
r7iz.4xlarge 16 128 Up to 12.5 Gbps Up to 10 Gbps
r7iz.8xlarge 32 256 12.5 Gbps 10 Gbps
r7iz.12xlarge 48 384 25 Gbps 19 Gbps
r7iz.16xlarge 64 512 25 Gbps 20 Gbps
r7iz.32xlarge 128 1024 50 Gbps 40 Gbps

You can attach up to 88 EBS volumes to each R7iz instance; by way of comparison, the z1d instances allow you to attach up to 28 volumes.

We are also getting ready to launch two sizes of bare metal R7iz instances:

vCPUs
Memory (GiB)
Network Bandwidth
EBS Bandwidth
r7iz.metal-16xl 64 512 25 Gbps 20 Gbps
r7iz.metal-32xl 128 1024 50 Gbps 40 Gbps

 Built-in Accelerators
R7iz instances also include four built-in accelerators: Advanced Matrix Extensions (AMX), Intel Data Streaming accelerator (DSA), Intel In-Memory Analytics Accelerator (IAA), and Intel QuickAssist Technology( QAT). Some of these accelerators require the use of specific kernel versions, drivers, and/or compilers. The Advanced Matrix Extensions are available on all sizes of R7iz instances while the Intel QAT, Intel IAA, and Intel DSA accelerators will be available on the r7iz.metal-16xl and r7iz.metal-32xl instances (coming soon).

Available Now
R7iz instances are generally available today in the US East (N. Virginia), and US West (Oregon) AWS Regions. As usual with Amazon EC2, you pay only for what you use. For more information, see Amazon EC2 pricing.

To learn more, visit our Amazon EC2 R7iz instances page, and please send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

Veliswa

How Vercel Shipped Cron Jobs in 2 Months Using Amazon EventBridge Scheduler

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/aws/how-vercel-shipped-cron-jobs-in-2-months-using-amazon-eventbridge-scheduler/

Vercel implemented Cron Jobs using Amazon EventBridge Scheduler, enabling their customers to create, manage, and run scheduled tasks at scale. The adoption of this feature was rapid, reaching over 7 million weekly cron invocations within a few months of release. This article shows how they did it and how they handle the massive scale they’re experiencing.

Vercel builds a front-end cloud that makes it easier for engineers to deploy and run their front-end applications. With more than 100 million deployments in Vercel in the last two years, Vercel helps users take advantage of best-in-class AWS infrastructure with zero configuration by relying heavily on serverless technology. Vercel provides a lot of features that help developers host their front-end applications. However, until the beginning of this year, they hadn’t built Cron Jobs yet.

A cron job is a scheduled task that automates running specific commands or scripts at predetermined intervals or fixed times. It enables users to set up regular, repetitive actions, such as backups, sending notification emails to customers, or processing payments when a subscription needs to be renewed. Cron jobs are widely used in computing environments to improve efficiency and automate routine operations, and they were a commonly requested feature from Vercel’s customers.

In December 2022, Vercel hosted an internal hackathon to foster innovation. That’s where Vincent Voyer and Andreas Schneider joined forces to build a prototype cron job feature for the Vercel platform. They formed a team of five people and worked on the feature for a week. The team worked on different tasks, from building a user interface to display the cron jobs to creating the backend implementation of the feature.

Amazon EventBridge Scheduler
When the hackathon team started thinking about solving the cron job problem, their first idea was to use Amazon EventBridge rules that run on a schedule. However, they realized quickly that this feature has a limit of 300 rules per account per AWS Region, which wasn’t enough for their intended use. Luckily, one of the team members had read the announcement of Amazon EventBridge Scheduler in the AWS Compute blog and they thought this would be a perfect tool for their problem.

By using EventBridge Scheduler, they could schedule one-time or recurrently millions of tasks across over 270 AWS services without provisioning or managing the underlying infrastructure.

How cron jobs work

For creating a new cron job in Vercel, a customer needs to define the frequency in which this task will run and the API they want to invoke. Vercel, in the backend, uses EventBridge Scheduler and creates a new schedule when a new cron job is created.

To call the endpoint, the team used an AWS Lambda function that receives the path that needs to be invoked as input parameters.

How cron jobs works

When the time comes for the cron job to run, EventBridge Scheduler invokes the function, which then calls the customer website endpoint that was configured.

By the end of the week, Vincent and his team had a working prototype version of the cron jobs feature, and they won a prize at the hackathon.

Building Vercel Cron Jobs
After working for one week on this prototype in December, the hackathon ended, and Vincent and his team returned to their regular jobs. In early January 2023, Vicent and the Vercel team decided to take the project and turn it into a real product.

During the hackathon, the team built the fundamental parts of the feature, but there were some details that they needed to polish to make it production ready. Vincent and Andreas worked on the feature, and in less than two months, on February 22, 2023, they announced Vercel Cron Jobs to the public. The announcement tweet got over 400 thousand views, and the community loved the launch.

Tweet from Vercel announcing cron jobs

The adoption of this feature was very rapid. Within a few months of launching Cron Jobs, Vercel reached over 7 million cron invocations per week, and they expect the adoption to continue growing.

Cron jobs adoption

How Vercel Cron Jobs Handles Scale
With this pace of adoption, scaling this feature is crucial for Vercel. In order to scale the amount of cron invocations at this pace, they had to make some business and architectural decisions.

From the business perspective, they defined limits for their free-tier customers. Free-tier customers can create a maximum of two cron jobs in their account, and they can only have hourly schedules. This means that free customers cannot run a cron job every 30 minutes; instead, they can do it at most every hour. Only customers on Vercel paid tiers can take advantage of EventBridge Scheduler minute granularity for scheduling tasks.

Also, for free customers, minute precision isn’t guaranteed. To achieve this, Vincent took advantage of the time window configuration from EventBridge Scheduler. The flexible time window configuration allows you to start a schedule within a window of time. This means that the scheduled tasks are dispersed across the time window to reduce the impact of multiple requests on downstream services. This is very useful if, for example, many customers want to run their jobs at midnight. By using the flexible time window, the load can spread across a set window of time.

From the architectural perspective, Vercel took advantage of hosting the APIs and owning the functions that the cron jobs invoke.

Validating the calls

This means that when the Lambda function is started by EventBridge Scheduler, the function ends its run without waiting for a response from the API. Then Vercel validates if the cron job ran by checking if the API and Vercel function ran correctly from its observability mechanisms. In this way, the function duration is very short, less than 400 milliseconds. This allows Vercel to run a lot of functions per second without affecting their concurrency limits.

Lambda invocations and duration dashboard

What Was The Impact?
Vercel’s implementation of Cron Jobs is an excellent example of what serverless technologies enable. In two months, with two people working full time, they were able to launch a feature that their community needed and enthusiastically adopted. This feature shows the completeness of Vercel’s platform and is an important feature to convince their customers to move to a paid account.

If you want to get started with EventBridge Scheduler, see Serverless Land patterns for EventBridge Scheduler, where you’ll find a broad range of examples to help you.

Marcia

Introducing Intra-VPC Communication Across Multiple Outposts with Direct VPC Routing

Post Syndicated from Macey Neff original https://aws.amazon.com/blogs/compute/introducing-intra-vpc-communication-across-multiple-outposts-with-direct-vpc-routing/

This blog post is written by Jared Thompson, Specialist Solutions Architect, Hybrid Edge.

Today, we announced AWS Outposts rack support for intra-VPC communication across multiple Outposts. You can now add routes in your Outposts rack subnet route table to forward traffic between subnets within the same VPC spanning across multiple Outposts using the Outpost local gateways (LGW). The LGW enables connectivity between your Outpost subnets and your on-premises network. With this enhancement, you can establish intra-VPC instance-to-instance IP communication across Outposts through your on-premise network, via direct VPC routing.

You can take advantage of this enhancement to architect for high availability for your on-premises applications and, at the same time, improve application performance by reducing the latency between application components that are in the same VPC but running on different Outposts.

This post shows you how you can use intra-VPC communication across multiple Outposts to build a Multi-AZ like architecture for your on-premises applications and services by leveraging direct VPC routing.

To clarify a few concepts before we go into the details: Outposts rack is the 42U form factor of the AWS Outposts Family of services. An Outpost is a pool of AWS compute and storage capacity deployed at a customer’s site. An Outpost may comprise of one or more racks connected together at the site.

Overview

Prior to today’s announcement, applications and services running on multiple Outposts were not able to communicate with each other if they were in the same VPC and if the Outpost was configured to use direct VPC routing. To overcome this limitation it was necessary to separate workloads into multiple VPCs and align each VPC with a separate Outpost, or to configure the Outpost local gateway route table to use Customer-owned IP (CoIP) mode. This limitation was because the traffic between two subnets that are in the same VPC but in disparate Outposts was not able to communicate each other through the service link, as it was blocked in the Region. (See the following diagram in Figure 1)

To show how this worked previously, as an example, let’s assume we have a VPC CIDR range of 10.77.0.0/16, and we want to route 10.77.11.0/24 using the local gateway:

When we attempted to apply this change, we would get the following error message:

The destination CIDR block 10.77.11.0/24 is equal or more specific than one of this VPC’s CIDR blocks. This route can target only an interface or an instance.

Because we were not able to specify a more specific route, we were not able to route between these subnets.

Prior to this feature, you could not send traffic to the local gateway, as you could not set a route that was more specific than the VPC's CIDR RangeFigure 1 – Prior to this feature, you could not send traffic to the local gateway, as you could not set a route that was more specific than the VPC’s CIDR Range

Using intra-VPC communication across multiple Outposts with direct VPC routing you can now define routes that are more specific than the local VPC CIDR range and has local gateway as target. This enables you to direct traffic from one subnet to another within the same VPC, using the Outpost’s local gateways (LGW). (See Figure 2)

Two Outpost racks in the same VPC can be configured to communicate over the Outpost local gateways

Figure 2 – Two Outpost racks in the same VPC can be configured to communicate over the Outpost local gateways

With this feature, you can design highly available architectures on the edge with multiple Outpost racks, eliminating the need to use multiple VPCs.

Let’s see it in action!

For this example, we will assume that we have a VPC CIDR of 10.77.0.0/16, Outpost A has a subnet CIDR of 10.77.7.0/24, and Outpost B has a subnet CIDR of 10.77.11.0/24.  By default, resources on these racks will not be able to communicate with each other since the default local route of each route table within the VPC is set to 10.77.0.0/16. If the traffic is on another Outpost, the traffic would be blocked because service link traffic cannot hairpin through the region. We are going to route this traffic across our on-premises infrastructure. (See Figure 3)

This is what our example environment looks like. Note, we have one VPC with two Outpost subnetsFigure 3 –This is what our example environment looks like. Note, we have one VPC with two Outpost subnets

For the purposes of this example, we are going to assume that the Customer WAN (See Figure 3) is already set up to route traffic between Outpost A and Outpost B subnets.  For more information, see Local gateway BGP connectivity in the AWS Outpost documentation.  Additionally, we will want to ensure that our local gateway routing tables are in direct VPC routing mode.

Let’s suppose that we want Instance A (10.77.7.88/24) to reach Instance B (10.77.11.119). We will try this with a ping:We can see that none of our pings worked. Since both of these subnets are on two different Outposts, we will need to configure our subnets to route traffic to each other by using intra-VPC communication across multiple Outposts with direct VPC routing.

To enable traffic between these two private subnets, we will configure the routing table to direct traffic towards the neighboring Outpost Subnet to use the Outpost local gateway, allowing traffic to flow between your on-premises network infrastructure. We do this by specifying a more specific route than the default VPC CIDR range.

1.To accomplish this, we will need to associate our VPC with the Outpost’s local gateway route table on each Outpost. From the console, navigate to AWS Outposts / Local gateway route tables. Find the local gateway route table that is associated with each Outpost, go to the VPC associations tab, and select Associate VPC.

Now that these VPC are associated to the local gateway routing table, we will be able to configure the route tables for these subnets to target the Outpost local gateway.

2. For our 10.77.7.0/24 subnet on Outpost Rack A, we will add a route to our other subnet, 10.77.11.0/24 in the subnet’s routing table. One of the target options is Outpost Local Gateway:

Selecting this option will bring up two options, for each of our local gateways. Be sure to select the correct local gateway ID for Outpost A’s local gateway, which is lgw-008e7656cf09c9c21 for my Outpost Rack A.

3. Do the same for our 10.77.11.0/24 subnet, this time setting a destination of 10.77.7.0/24 via the local gateway ID of Outpost Rack B:

Now that we have our routes updated, let’s try our ping again.

Success! We are now able to reach the other instance over the local gateways. This is because our route tables in the Outposts subnets are forwarding traffic over the local gateway, utilizing our on-premises network infrastructure for the communication backbone.

Availability

Intra-VPC communication across multiple Outposts with direct VPC routing is available in all AWS Regions where Outposts rack is available. Your existing Outposts racks may require an update to enable support for Intra-VPC communication across multiple Outposts. If this feature does not work for you, please contact AWS Support.

Conclusion

Utilizing intra-VPC communication across Outposts with direct VPC routing allows you to route traffic between subnets within the same VPC. This feature will allow traffic to route across different Outposts by utilizing Outposts local gateway and your on-premises network, without needing to divide your infrastructure into multiple VPCs. You can take advantage of this enhancement for your on-premises applications, while improving application performance by reducing latency between application components running on multiple Outposts.

Let’s Architect! Cost-optimizing AWS workloads

Post Syndicated from Luca Mezzalira original https://aws.amazon.com/blogs/architecture/lets-architect-cost-optimizing-aws-workloads/

Every software component built by engineers and architects is designed with a purpose: to offer particular functionalities and, ultimately, contribute to the generation of business value. We should consider fundamental factors, such as the scalability of the software and the ease of evolution during times of business changes. However, performance and cost are important factors as well since they can impact the business profitability.

This edition of Let’s Architect! follows a similar series post from 2022, which discusses optimizing the cost of an architecture. Today, we focus on architectural patterns, services, and best practices to design cost-optimized cloud workloads. We also want to identify solutions, such as the use of Graviton processors, for increased performance at lower price. Cost optimization is a continuous process that requires the identification of the right tools for each job, as well as the adoption of efficient designs for your system.

AWS re:Invent 2022 – Manage and control your AWS costs

Govern cloud usage and avoid cost surprises without slowing down innovation within your organization. In this re:Invent 2022 session, you can learn how to set up guardrails and operationalize cost control within your organizations using services, such as AWS Budgets and AWS Cost Anomaly Detection, and explore the latest enhancements in the AWS cost control space. Additionally, Mercado Libre shares how they automate their cloud cost control through central management and automated algorithms.

Take me to this re:Invent 2022 video!

Work backwards from team needs to define/deploy cloud governance in AWS environments

Work backwards from team needs to define/deploy cloud governance in AWS environments

Compute optimization

When it comes to optimizing compute workloads, there are many tools available, such as AWS Compute Optimizer, Amazon EC2 Spot Instances, Amazon EC2 Reserved Instances, and Graviton instances. Modernizing your applications can also lead to cost savings, but you need to know how to use the right tools and techniques in an effective and efficient way.

For AWS Lambda functions, you can use the AWS Lambda Cost Optimization video to learn how to optimize your costs. The video covers topics, such as understanding and graphing performance versus cost, code optimization techniques, and avoiding idle wait time. If you are using Amazon Elastic Container Service (Amazon ECS) and AWS Fargate, you can watch a Twitch video on cost optimization using Amazon ECS and AWS Fargate to learn how to adjust your costs. The video covers topics like using spot instances, choosing the right instance type, and using Fargate Spot.

Finally, with Amazon Elastic Kubernetes Service (Amazon EKS), you can use Karpenter, an open-source Kubernetes cluster auto scaler to help optimize compute workloads. Karpenter can help you launch right-sized compute resources in response to changing application load, help you adopt spot and Graviton instances. To learn more about Karpenter, read the post How CoStar uses Karpenter to optimize their Amazon EKS Resources on the AWS Containers Blog.

Take me to Cost Optimization using Amazon ECS and AWS Fargate!
Take me to AWS Lambda Cost Optimization!
Take me to How CoStar uses Karpenter to optimize their Amazon EKS Resources!

Karpenter launches and terminates nodes to reduce infrastructure costs

Karpenter launches and terminates nodes to reduce infrastructure costs

AWS Lambda general guidance for cost optimization

AWS Lambda general guidance for cost optimization

AWS Graviton deep dive: The best price performance for AWS workloads

The choice of the hardware is a fundamental driver for performance, cost, as well as resource consumption of the systems we build. Graviton is a family of processors designed by AWS to support cloud-based workloads and give improvements in terms of performance and cost. This re:Invent 2022 presentation introduces Graviton and addresses the problems it can solve, how the underlying CPU architecture is designed, and how to get started with it. Furthermore, you can learn the journey to move different types of workloads to this architecture, such as containers, Java applications, and C applications.

Take me to this re:Invent 2022 video!

AWS Graviton processors are specifically designed by AWS for cloud workloads to deliver the best price performance

AWS Graviton processors are specifically designed by AWS for cloud workloads to deliver the best price performance

AWS Well-Architected Labs: Cost Optimization

The Cost Optimization section of the AWS Well Architected Workshop helps you learn how to optimize your AWS costs by using features, such as AWS Compute Optimizer, Spot Instances, and Reserved Instances. The workshop includes hands-on labs that walk you through the process of optimizing costs for different types of workloads and services, such as Amazon Elastic Compute Cloud, Amazon ECS, and Lambda.

Take me to this AWS Well-Architected lab!

Savings Plans is a flexible pricing model that can help reduce expenses compared with on-demand pricing

Savings Plans is a flexible pricing model that can help reduce expenses compared with on-demand pricing

See you next time!

Thanks for joining us to discuss cost optimization! In 2 weeks, we’ll talk about in-memory databases and caching systems.

To find all the blogs from this series, visit the Let’s Architect! list of content on the AWS Architecture Blog.

Providing durable storage for AWS Outpost servers using AWS Snowcone

Post Syndicated from Macey Neff original https://aws.amazon.com/blogs/compute/providing-durable-storage-for-aws-outpost-servers-using-aws-snowcone/

This blog post is written by Rob Goodwin, Specialist Solutions Architect, Secure Hybrid Edge. 

With the announcement of AWS Outposts servers, you now have a streamlined means to deploy AWS Cloud infrastructure to regional offices using the 1 rack unit (1U) or 2 rack unit (2U) Outposts servers where the 42U AWS Outposts rack wasn’t an economical or physical fit.

This post discusses how you can use AWS Snowcone to provide persistent storage for AWS Outposts servers in the case of Amazon Elastic Compute Cloud (Amazon EC2) instance termination or if the Outposts server fails. In this post, we show:

  1. How to leverage the built-in features of Snowcone to provide persistent storage to an EC2 instance.
  2. Optionally replicate the data back to an AWS Region with AWS DataSync. Replicating data back to an AWS Region with DataSync allows for a seamless way to copy data offsite to improve resiliency. Furthermore, it allows the ability to leverage regional AWS Services for machine learning (ML) training.

Background

Outposts servers ship with internal NVMe SSD instance storage. Just like in the Regions, instance storage is allocated directly to the EC2 instance and tied to the lifecycle of the instance. This means that if the EC2 instance is terminated, then the data associated with the instance is deleted. In the event you want data to persist after the instance is terminated, you must use operating system (OS) functions to save and back up to other media or save your data to an external network attached storage or file system.

Mounting an external file system to an EC2 instance is not a new concept in AWS. Using Amazon Elastic File System (Amazon EFS), you can mount the EFS file system to EC2 instance(s).

This architecture may look similar to the following diagram:

AWS VPC showing EC2 Instances mounting Amazon EFS in the Region

Figure 1: AWS VPC showing EC2 Instances mounting Amazon EFS in the Region

In this architecture, EC2 instances are using Amazon EFS for a shared file system.

A main use case for Outposts servers is to deploy applications closer to an end user for quicker response times. If we move our application to the Outposts server to improve the response time to the end user, then we could still use Amazon EFS as a shared file system. However, the latency to read the file system over the service link may affect application performance.

There are third-party network attached storage systems available that could work with Outposts servers. However, Snowcone provides the built-in service of DataSync to replicate data back to the Region and is ideal where physical space and power are limited.

By leveraging Snowcone, we can provide persistent and durable network attached storage external to the Outposts server along with a means to replicate data to and from an AWS Region. Snowcone is a small, rugged, and secure device offering edge computing, data storage, and data transfer.

Solution overview

In this solution, we combine multiple AWS services to provide a durable environment. We use Snowcone as our Network File System (NFS) mount point and leverage the built-in DataSync Agent to replicate the bucket on the Snowcone back to an Amazon Simple Storage Service (Amazon S3) bucket in-Region.

When EC2 instances are launched on the Outposts server, we map the NFS mount point from the Snowcone into the file system of a Linux host through the Outposts server’s Logical Network Interface (LNI). For a Windows system, using the NFS Client for Windows, we can map a drive letter to the NFS mount point as well. The following diagram illustrates this.

EC2 instances on Outposts server attaching to the NFS mount on Snowcone with DataSync replicating data back to Amazon S3 in the AWS Region

Figure 2: EC2 instances on Outposts server attaching to the NFS mount on Snowcone with DataSync replicating data back to Amazon S3 in the AWS Region

Prerequisites

To deploy this solution, you must:

  1. Have the Outposts server installed and authorized.
    1. The Outposts server must be fully capable of launching an EC2 instance and being able to communicate through the LNI to local network resources.
  2. Have an AWS Snowcone ordered, connected to the local network, and unlocked.
    1. To make sure that NFS is available, the job type must be either Import into Amazon S3 or Export from Amazon S3, as shown in the following figure.
    1. Figure 3: Screenshot of Job Type when ordering Snow devices
  3. Have a local client with AWS OpsHub installed.
    1. You can use an instance launched on the Outposts server to configure the Snowcone if:
      1. ·       The LNI is connected on the instance
      2. ·       The Snowcone is on the network

Steps to activate

  1. Configure NFS on the Snowcone manually.
    1. Either statically assign the IP address, or if you’re using DHCP, create an IP reservation to make sure that the NFS mount is consistent. In the following figure, we use 10.0.0.32 as a static IP assigned to the NFS Mount.
  2. (Optional) Start the DataSync Agent on the Snowcone.
    1. We assume that the Snowcone has access to the internet in the same way the Outposts server does. Configure the Agent, and then enable tasks. The Agent is used to replicate data from the Snowcone to the Region or from the Region to the Snowcone. The tasks that are created in this step enable replication.
  3. Launch the EC2 instance (either a. or b.)
    1. a.      Using a Linux OS – When launching an instance on the Outposts server to attach to the NFS mount, make sure that the LNI is configured when launching the instance. In the User data section, enter the commands shown in the following figure to mount the NFS file system from the Snowcone.Screenshot of User Data section within the Amazon EC2 Launch Wizard

Figure 5: Screenshot of User Data section within the Amazon EC2 Launch Wizard

#!/bin/bash
sudo mkdir /var/snowcone
sudo mount -t nfs SNOW-NFS-IP:/buckets /var/snowcone
sudo sh -c “echo ’ SNOW-NFS-IP:/buckets /var/snowcone nfs defaults 0 0’ >> /etc/fstab”

In this OS, we create a directory and then mount the NFS file system to that directory. The echo is used to place the mount into fstab to make sure that the mount is persistent if the instance is rebooted.

  1. b        Windows OS – The AMI being used during the launch must include the NFS client. The client is required to mount the NFS. When launching an instance on the Outposts server to attach to the NFS mount, make sure that the LNI is configured when launching the instance. In the User data section, enter the commands shown in the following figure to mount the NFS from the Snowcone as a drive letter.

A screenshot of User Data section of Amazon EC2 Launch wizard with commands to mount NFS to the Windows File System

Figure 6: A screenshot of User Data section of Amazon EC2 Launch wizard with commands to mount NFS to the Windows File System

<powershell>
NET USE Z: \\SNOW-NFS-IP\buckets -P
</powershell> 

The NET USE command maps the Z: drive to the NFS mount, and the -P makes it persistent between reboots.

This solution also works with Snowball Edge Storage Optimized. When ordering the Snowball Edge, choose NFS based data transfer for the storage type.

Screenshot of Select the storage type for the Snowball Edge

Figure 4: Screenshot of Select the storage type for the Snowball Edge

Conclusion

In this post, we examined how to mount NFS file systems in Snowcone to EC2 instances running on Outposts servers. We also covered starting DataSync Agent on Snowcone to enable data transfer from the edge to an AWS Region. By pairing these services together, you can build persistent and durable storage external to the Outposts servers and replicate your data back to the AWS Region.

If you want to learn more about how to get started with Outposts servers, my colleague Josh Coen and I have published a video series on this topic. The demo series shows you how to unbox an Outposts server, activate the Outposts server, and what you can do with your Outposts server after it is activated. Make sure to check it out!

New – Amazon EC2 Hpc7a Instances Powered by 4th Gen AMD EPYC Processors Optimized for High Performance Computing

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/new-amazon-ec2-hpc7a-instances-powered-by-4th-gen-amd-epyc-processors-optimized-for-high-performance-computing/

In January 2022, we launched Amazon EC2 Hpc6a instances for customers to efficiently run their compute-bound high performance computing (HPC) workloads on AWS with up to 65 percent better price performance over comparable x86-based compute-optimized instances.

As their jobs grow more complex, customers have asked for more cores with more compute performance and more memory and network performance to reduce the time to complete jobs. Additionally, as customers look to bring more of their HPC workloads to EC2, they have asked how we can make it easier to distribute processes to make the best use of memory and network bandwidth, to align with their workload requirements.

Today, we are announcing the general availability of Amazon EC2 Hpc7a instances, the next generation of instance types that are purpose-built for tightly coupled HPC workloads. Hpc7a instances powered by the 4th Gen AMD EPYC processors (Genoa) deliver up to 2.5 times better performance compared to Hpc6a instances. These instances offer 300 Gbps Elastic Fabric Adapter (EFA) bandwidth powered by the AWS Nitro System, for fast and low-latency internode communications.

Hpc7a instances feature Double Data Rate 5 (DDR5) memory, which provides 50 percent higher memory bandwidth compared to DDR4 memory to enable high-speed access to data in memory. These instances are ideal for compute-intensive, latency-sensitive workloads such as computational fluid dynamics (CFD) and numerical weather prediction (NWP).

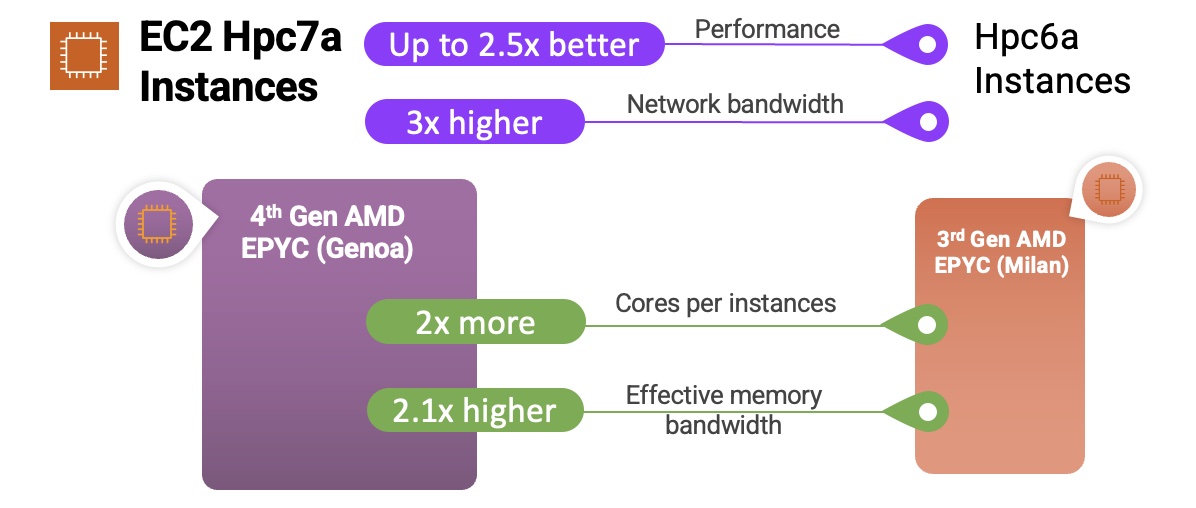
If you are running on Hpc6a, you can use Hpc7a instances and take advantage of the 2 times higher core density, 2.1 times higher effective memory bandwidth, and 3 times higher network bandwidth to lower the time needed to complete jobs compared to Hpc6a instances.

Here’s a quick infographic that shows you how the Hpc7a instances and the 4th Gen AMD EPYC processor (Genoa) compare to the previous instances and processor:

Hpc7a instances feature sizes of up to 192 cores of the AMD EPYC processors CPUs with 768 GiB RAM. Here are the detailed specs:

Instance Name CPUs RAM (Gib)
EFA Network Bandwidth (Gbps)
Attached Storage
Hpc7a.12xlarge 24 768 Up to 300 EBS Only
Hpc7a.24xlarge 48 768 Up to 300 EBS Only
Hpc7a.48xlarge 96 768 Up to 300 EBS Only
Hpc7a.96xlarge 192 768 Up to 300 EBS Only

These instances provide higher compute, memory, and network performance to run the most compute-intensive workloads, such as CFD, weather forecasting, molecular dynamics, and computational chemistry on AWS.

Similar to EC2 Hpc7g instances released a month earlier, we are offering smaller instance sizes that makes it easier for customers to pick a smaller number of CPU cores to activate while keeping all other resources constant based on their workload requirements. For HPC workloads, common scenarios include providing more memory bandwidth per core for CFD workloads, allocating fewer cores in license-bound scenarios, and supporting more memory per core. To learn more, see Instance sizes in the Amazon EC2 Hpc7 family – a different experience in the AWS HPC Blog.

As with Hpc6a instances, you can use the Hpc7a instance to run your largest and most complex HPC simulations on EC2 and optimize for cost and performance. You can also use the new Hpc7a instances with AWS Batch and AWS ParallelCluster to simplify workload submission and cluster creation. You can also use Amazon FSx for Lustre for submillisecond latencies and up to hundreds of gigabytes per second of throughput for storage.

To achieve the best performance for HPC workloads, these instances have Simultaneous Multithreading (SMT) disabled, they’re available in a single Availability Zone, and they have limited external network and EBS bandwidth.

Now Available
Amazon EC2 Hpc7a instances are available today in three AWS Regions: US East (Ohio), EU (Ireland), and US GovCloud for purchase in On-Demand, Reserved Instances, and Savings Plans. For more information, see the Amazon EC2 pricing page.

To learn more, visit our Hpc7a instances page and get in touch with our HPC team, AWS re:Post for EC2, or through your usual AWS Support contacts.

Channy

New – Amazon EC2 M7a General Purpose Instances Powered by 4th Gen AMD EPYC Processors

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/new-amazon-ec2-m7a-general-purpose-instances-powered-by-4th-gen-amd-epyc-processors/

In November 2021, we launched Amazon EC2 M6a instances, powered by 3rd Gen AMD EPYC (Milan) processors, running at frequencies up to 3.6 GHz, which offer you up to 35 percent improvement in price performance compared to M5a instances. Many customers who run workloads that are dependent on x86 instructions, such as SAP, are looking for ways to optimize their cloud utilization. They’re taking advantage of the compute choice that EC2 offers.

Today, we’re announcing the general availability of new, general purpose Amazon EC2 M7a instances, powered by the 4th Gen AMD EPYC (Genoa) processors with a maximum frequency of 3.7 GHz, which offer up to 50 percent higher performance compared to M6a instances. This increased performance gives you the ability to process data faster, consolidate workloads, and lower the cost of ownership.

M7a instances support AVX-512, Vector Neural Network Instructions (VNNI) and brain floating point (bfloat16). These instances feature Double Data Rate 5 (DDR5) memory, which enable high-speed access to data in-memory, and deliver 2.25 times more memory bandwidth compared to M6a instances for lower latency.

M7a instances are SAP-certified and ideal for applications that benefit from high performance and high throughput, such as financial applications, application servers, simulation modeling, gaming, mid-size data stores, application development environments, and caching fleets.

M7a instances feature sizes of up to 192 vCPUs with 768 GiB RAM. Here are the detailed specs:

Name vCPUs Memory (GiB) Network Bandwidth (Gbps) EBS Bandwidth (Gbps)
m7a.medium 1 4 Up to 12.5 Up to 10
m7a.large 2 8 Up to 12.5 Up to 10
m7a.xlarge 4 16 Up to 12.5 Up to 10
m7a.2xlarge 8 32 Up to 12.5 Up to 10
m7a.4xlarge 16 64 Up to 12.5 Up to 10
m7a.8xlarge 32 128 12.5 10
m7a.12xlarge 48 192 18.75 15
m7a.16xlarge 64 256 25 20
m7a.24xlarge 96 384 37.5 30
m7a.32xlarge 128 512 50 40
m7a.48xlarge 192 768 50 40
m7a.metal-48xl 192 768 50 40

M7a instances have up to 50 Gbps enhanced networking and 40 Gbps EBS bandwidth, which is similar to M6a instances. But you have a new medium instance size, which enables you to right-size your workloads more accurately, offering 1 vCPUs, 4 GiB, and the largest size offering 192 vCPUs, 768 GiB.

The new instances are built on the AWS Nitro System, a collection of building blocks that offloads many of the traditional virtualization functions to dedicated hardware for high performance, high availability, and highly secure cloud instances.

Now Available
Amazon EC2 M7a instances are now available today in AWS Regions: US East (Ohio), US East (N. Virginia), US West (Oregon), and EU (Ireland). As usual with Amazon EC2, you only pay for what you use. For more information, see the Amazon EC2 pricing page.

To learn more, visit the EC2 M7a instance and AWS/AMD partner page. You can send feedback to [email protected], AWS re:Post for EC2, or through your usual AWS Support contacts.

Channy

Create, Use, and Troubleshoot Launch Scripts on Amazon Lightsail

Post Syndicated from Macey Neff original https://aws.amazon.com/blogs/compute/create-use-and-troubleshoot-launch-scripts-on-amazon-lightsail/

This blog post is written by Brian Graf, Senior Developer Advocate, Amazon Lightsail and Sophia Parafina, Senior Developer Advocate. 

Amazon Lightsail is a virtual private server (VPS) for deploying both operating systems (OS) and pre-packaged applications, such as WordPress, Plesk, cPanel, PrestaShop, and more. When deploying these instances, you can run launch scripts with additional commands such as installation of applications, configuration of system files, or installing pre-requisites for your application.

Where do I add a launch script?

If you’re deploying an instance with the Lightsail console, launch scripts can be added to an instance at deployment. They are added in the ‘deploy instance’ page:

Image of Amazon Lightsail deploy an instance page

The launch script must be added before the instance is deployed, because launch scripts can’t retroactively run after deployment.

Anatomy of a Windows Launch Script

When deploying a Lightsail Windows instance, you can use a batch script or a PowerShell script in the ‘launch script’ textbox.  Of the two options, PowerShell is more extensible and provides greater flexibility for configuration and control.

If you choose to write your launch script as a batch file, you must add <script> </script> tags at the beginning and end of your code respectively. Alternatively, a launch script in PowerShell, must use the <powershell></powershell> tags in a similar fashion.

After the closing </script> or </powershell> tag, you must add a <persist></persist> tag on the following line. The persist tag is used to determine if this is a run-once command or if it should run every time your instance is rebooted or changed from the ‘Stop’ to ‘Start’ state. If you want your script to run every time the instance is rebooted or started, then you must set the persist tag to ‘true’. If you want your launch script to just run once, then you would set your persist tag to ‘false’.

Anatomy of a Linux Launch Script

Like a Windows launch script, a Linux launch script requires specific code on the first row of the textbox to successfully execute during deployment. You must place ‘#!/bin/bash’ as the first line of code to set the shell that executes the rest of the script. After first line of code, you can continue adding additional commands to achieve the results you want.

How do I know if my Launch Script ran successfully?

Although running launch scripts is convenient to create a baseline instance, it’s possible that your instance doesn’t achieve the desired end-state because of an error in your script or permissions issues. You must troubleshoot to see why the launch script didn’t complete successfully. To find if the launch script ran successfully, refer to the instance logs to determine whether your launch script was successful or not.

For Windows, the launch log can be found in: C:\ProgramData\Amazon\EC2-Windows\launch\Log\UserdataExecution.log. Note that ProgramData is a hidden folder, and unless you access the file from PowerShell or Command Prompt, you must use Windows File Explorer (`View > Show > Hidden items`) folders to see it.

For Linux, the launch log can be found in: /var/log/cloud-init-output.log and can be monitored after your instance launches by tailing the log by typing the following in the terminal:

tail -f /var/log/cloud-init-output.log

If you want to see the entire log file including commands that have already run before you opened the log file, then you can type the following in the terminal:

less +F /var/log/cloud-init-output.log

On a Windows instance, an easy way to monitor the UserdataExecution.log is to add the following code in your launch script, which creates a shortcut to tail or watch the log as commands are executing:

# Create a log-monitoring script to monitor the progress of the launch script execution

$monitorlogs = @"
get-content C:\ProgramData\Amazon\EC2-Windows\launch\Log\UserdataExecution.log -wait
"@

# Save the log-monitoring script to the desktop for the user

$monitorlogs | out-file -FilePath C:\Users\Administrator\Desktop\MonitorLogs.ps1 -Encoding utf8 -Force

</powershell>
<persist>false</persist>

If the script was executed, then the last line of the log should say ‘{Timestamp}: User data script completed’.

However, if you want more detail, you can build the logging into your launch script. For example, you can append a text or log file with each command so that you can read the output in an easy-to-access location:

<powershell>
# Set the location for the log file. In this case,
# it will appear on the desktop of your Lightsail instance
$loc = "c:\Users\Administrator\Desktop\mylog.txt"

# Write text to the log file
Write-Output "Starting Script" >> $loc

# Download and install Chocolatey to do unattended installations of the rest of the apps.
iex ((New-Object System.Net.WebClient).DownloadString('https://chocolatey.org/install.ps1'))

# You could run commands like this to output the progress to the log file:

# Install vscode and all dependencies
choco install -y vscode --force --force-dependencies --verbose >> $loc

# Install git and all dependencies
choco install -y git --force --force-dependencies --verbose >> $loc

# Completed
Write-Output "Completed" >> $loc
</powershell>
<persist>false</persist>

This code creates a log file, outputs data, and appends it along the way. If there is an issue, then you can see where the logs stopped or errors appeared.

For Ubuntu and Amazon Linux 2

If the cloud-init-output.log isn’t comprehensive enough, then you can re-direct the output from your commands to a log file of your choice. In this example, we create a log file in the /tmp/ directory and push all output from our commands to this file.

# Create the log file
touch /tmp/launchscript.log

# Add text to the log file if you so choose
echo 'Starting' >> /tmp/launchscript.log

# Update package index
sudo apt update >> /tmp/launchscript.log

# Install software to manage independent software vendor sources
sudo apt -y install software-properties-common >> /tmp/launchscript.log

# Add the repository for all PHP versions
sudo add-apt-repository -y ppa:ondrej/php >> /tmp/launchscript.log

# Install Web server, mySQL client, PHP (and packages), unzip, and curl
sudo apt -y install apache2 mysql-client-core-8.0 php8.0 libapache2-mod-php8.0 php8.0-common php8.0-imap php8.0-mbstring php8.0-xmlrpc php8.0-soap php8.0-gd php8.0-xml php8.0-intl php8.0-mysql php8.0-cli php8.0-bcmath php8.0-ldap php8.0-zip php8.0-curl unzip curl >> /tmp/launchscript.log

# Any final text you want to include
echo 'Completed' >> /tmp/launchscript.log

It’s possible to check the logs before the launch script has finished executing. One way to follow along is to ‘tail’ the log file. This lets you stream all updates as they occur. You can monitor the log using:

‘tail -f /tmp/launchscript.log’. </code>

Using Launch Scripts from AWS Command Line Interface (AWS CLI)

You can deploy their Lightsail instances from the AWS Command Line Interface (AWS CLI) instead of the Lightsail console. You can add launch scripts to the AWS CLI command as a parameter by creating a variable with the script and referencing the variable, or by saving the launch script as a file and referencing the local file location on your computer.

The launch script is still written the same way as the previous examples. For a Windows instance with a PowerShell launch script, you can deploy a Lightsail instance with a launch script with the following code:

# PowerShell script saved in the Downloads folder:

$loc = "c:\Users\Administrator\Desktop\mylog.txt"

# Write text to the log file

Write-Output "Starting Script" >> $loc

# Download and install Chocolatey to do unattended installations of the rest of the apps.

iex ((New-Object System.Net.WebClient).DownloadString('https://chocolatey.org/install.ps1'))

# You could run commands like this to output the progress to the log file:

# Install vscode and all dependencies

choco install -y vscode --force --force-dependencies --verbose >> $loc

# Install git and all dependencies

choco install -y git --force --force-dependencies --verbose >> $loc

# Completed

Write-Output "Completed" >> $loc

AWS CLI code to deploy a Windows Server 2019 medium instance in the us-west-2a Availability Zone:

aws lightsail create-instances \

--instance-names "my-windows-instance-1" \

--availability-zone us-west-2a \

--blueprint-id windows_server_2019 \

--bundle-id medium_win_2_0 \

--region us-west-2 \

--user-data file://~/Downloads/powershell_script.ps1

Clean up

Remember to delete resources when you are finished using them to avoid incurring future costs.

Conclusion

You now have the understanding and examples of how to create and troubleshoot Lightsail launch scripts both through the Lightsail console and AWS CLI. As demonstrated in this blog, using launch scripts, you can increase your productivity and decrease the deployment time and configuration of your applications. For more examples of using launch scripts, check out the aws-samples GitHub repository. You now have all the foundational building blocks you need to successfully script automated instance configuration. To learn more about Lightsail, visit the Lightsail service page.

Building a high-performance Windows workstation on AWS for graphics intensive applications

Post Syndicated from Macey Neff original https://aws.amazon.com/blogs/compute/building-a-high-performance-windows-workstation-on-aws-for-graphics-intensive-applications/

This blog post is written by Mike Lim, Senior Public Sector SA.

Video editing, professional visualization, and video games can be resource demanding applications that require high performance Windows workstations with GPUs. When developing these resource demanding applications, a high-performance remote display protocol is desirable in order to access the instances’ graphical desktops from the internet. Using NICE DCV provides a bandwidth-adaptive streaming protocol that provides near real-time responsiveness without compromising image quality. Customers using NICE DCV can leverage Amazon EC2 G4 and Amazon EC2 G5 GPU instances which support graphic-intensive applications in the cloud using a pay-as-you-go pricing model. By using Amazon Elastic Compute Cloud (Amazon EC2) with NICE DCV, customers can run graphically intensive applications remotely and stream their user interface to simpler client machines, eliminating the need for expensive dedicated workstations.

This post shows how you can provision and manage an Amazon EC2 GPU Windows instance and access it via the high-performance NICE DCV remote display protocol.

Solution overview

The solution is illustrated in the following figure.

Solution overview

Figure 1: Solution overview

We used the AWS CloudFormation Infrastructure-as-Code (IaC) service to provision our solution. Our CloudFormation template provides the following functionality:

1.       Using AWS CloudFormation, you can specify your choice of EC2 instance type, the Amazon Virtual Private Cloud (Amazon VPC), and subnet in which to provision. You also have the option to assign a static IPv4 address. NICE DCV server is installed to provide remote access, and you can specify the choice of graphics driver to install.

2.       A security group is created and associated with the EC2 instance, and it acts as a firewall.

3.       An AWS Identity and Access Management (IAM) role is created and associated with the EC2 instance using an instance profile. It lets your instance access Amazon Simple Storage Service (Amazon S3) buckets for NICE DCV server license validation, and download and install the latest graphics drivers.

4.       The IAM role also makes sure that your EC2 instance can be managed by AWS Systems Manager. This service provides in-browser command line and graphical access to your Windows instance via Session Manager and Fleet Manager from the AWS Management Console.

Walkthrough

The following sections walk through the steps to setup and maintain your graphics workstation. To begin, you need an AWS account. For this walkthrough, we provision a g5.xlarge instance for cloud gaming.

Check instance type availability

For best performance and lowest latency, you will want to provision EC2 in the AWS Region nearest to you. Before proceeding, verify that the g5.xlarge instance type is available in your desired AWS Region, and the Availability Zones (AZs) in which it is available.

Log in to your Amazon EC2 console and select your AWS Region. From the navigation pane, choose Instance Types to view the instance types available. In the search bar, filter instances types to the specific instance type you want, in this case g5.xlarge. Toggle the display preferences (gear) icon to display Availability zones column.

In the following screenshot, the g5.xlarge instance is available in two of the three AZs in eu-west-2 Europe London Region.

Amazon EC2 console instance types

Figure 2: Amazon EC2 console instance types

Check Amazon EC2 running on-demand G instances quota

Your AWS account has a limit on the number and type of EC2 instances types you can run, and you need to make sure you have enough quota to run the g5.xlarge instance.

Go to the Service Quotas console for your AWS Region. Under AWS services in the navigation pane, select Amazon Elastic Compute Cloud (Amazon EC2) and search for Running On-Demand G and VT instances. Verify that the Applied quota value number is equal or more than the number of vCPUs for the instance size you need. In the following screenshot, the applied quota value is 64. It lets us launch instance sizes from 4 vCPUs xlarge up to 64 vCPUs 16xlarge instance size.

Service Quotas console

Figure 3: Service Quotas console

You can request a higher quota value by selecting Request quota increase.

Using CloudFormation template

Download the CloudFormation template file from aws-samples GitHub repository. Go to the CloudFormation console for your AWS Region to create a stack, and upload your downloaded file.

The CloudFormation parameters page is divided into the following sections:

  1. AMI and instance type
  2. EC2 configuration
  3. Allowed inbound source IP prefixes to NICE DCV port 8443
  4. EBS volume configuration

We go through the configuration settings for each section in detail.

AMI and instance type

In this section, we select the Windows Amazon Machine Image (AMI) to use, EC2 instance type to provision, and graphics driver to install. The default AMI is Microsoft Windows Server 2022.

Replace the instanceType value with g5.xlarge.

CloudFormation parameters: AMI and instance type

Figure 4: CloudFormation parameters: AMI and instance type

Select driverType based on your instance type and the following use case:

  1. AMD: select this for instance types with AMD GPU (G4ad instance).
  2. NVIDIA-Gaming: select this to install the NVIDIA gaming driver, which is optimized for gaming (G5 and G4dn instances).
  3. NVIDIA-GRID: select this to install the GRID driver, which is optimized for professional visualization applications that render content such as 3D models or high-resolution videos (G5, G4dn, and G3 instances).
  4. none: select this option for accelerated computing instances, such as P2 and P3 instances where you download and install public NVIDIA drivers manually.
  5. NICE-DCV: this installs the NICE DCV Virtual Display driver and is suitable for all other instance types.

Note that GRID and NVIDIA gaming drivers’ downloads are available to AWS customers only. Upon installation of the software, you are bound by the terms of the NVIDIA GRID Cloud End User License Agreement.

For our walkthrough, select NVIDIA-Gaming for driverType.

Amazon EC2 configuration

In this section, we specify the VPC and subnet in which to provision our EC2 instance. You can select default VPC from the vpcID dropdown. Make sure that the subnetID value you select is in your selected VPC and resides in an AZ that has your instance type offering. You can also change the EC2 instance name.

Select Yes for the assignStaticIP option if you want to associate a static Internet IPv4 address. Note that there is a small hourly charge when the instance is not running.

CloudFormation parameters: Amazon EC2 configuration

Figure 5: CloudFormation parameters: Amazon EC2 configuration

Allowed inbound source IP prefixes to NICE DCV port 8443

Here, we specify the source prefixes allowed to access our instance. The default values allow access from all addresses. To secure access to your instance, you may want to limit the source prefix to your IP address.

To get your IPv4 address, go to https://checkip.amazonaws.com and append /32 to the value for ingressIPv4. The default VPC and subnet is IPv4 only. Therefore, you can enter ::1/128 to explicitly block all IPv6 access for ingressIPv6.

CloudFormation parameters: Allowed inbound source IP prefixes

Figure 6: CloudFormation parameters: Allowed inbound source IP prefixes

Amazon EBS volume configuration

The default Amazon Elastic Block Store (Amazon EBS) volume size is 30 GiB. You can specify a larger size by changing the volumeSize value.

CloudFormation parameters: Amazon EBS volume configuration

Figure 7: CloudFormation parameters: Amazon EBS volume configuration

Continue to provision your stack.

NICE DCV client

NICE DCV provides an HTML5 client for web browser access. For performance and additional features, such as QUIC UDP transport protocol support and USB remotization support, install the native client from the NICE DCV download page. NICE DCV offers native clients for Windows, MacOS for both Intel and Apple M1 processors, and modern Linux distributions including RHEL, SUSE Linux, and Ubuntu.

Cloudformation Outputs

Once provisioning is complete, go to the Outputs section.

CloudFormation Outputs

Figure 8: CloudFormation Outputs

The following URLs are available.

  1. DCVwebConsole
  2. EC2instance
  3. RdpConnect
  4. SSMsessionManager

We go through the purpose of each URL in the following sections.

SSMsessionManager: Change administrator password

To log in, you must specify an administrator password. Open the SSMsessionManager value URL in a new browser tab and run the command net user administrator <YOUR-PASSWORD> where <YOUR-PASSWORD> is the password on which you decided.

Systems Manager session manager

Figure 9: Systems Manager session manager

DCVwebConsole: Connecting to the EC2 instance

Copy DCVWebConsole value, open the NICE DCV client from your local machine and either use the copied value or the IP address to connect. Log in as administrator with the password that you have configured. Alternatively, enter the URL in the format dcv://<EC2-IP-Address> in a browser URL bar to automatically launch and connect a locally installed NICE DCV client to your EC2 instance.

NICE DCV client

Figure 10: NICE DCV client

EC2instance: manage EC2 instance

Use this link to manage your EC2 instance in the Amazon EC2 console. If you did not select the static IP address option, then use this page to get the assigned IP address whenever you stop and start your instance.

RdpConnect: Fleet Manager console access

The RdpConnect link provides in-browser Remote Desktop Protocol (RDP) console access to your Windows instance. Choose User credentials for Authentication Type. Enter administrator for username and the password that you have configured.

Fleet Manager Remote Desktop

Figure 11: Fleet Manager Remote Desktop

Updating NICE DCV server

To update NICE DCV server, log in via Fleet Manager Remote Desktop and run c:\users\administrator\update-DCV.cmd script. In the following screenshot, we successfully upgraded NICE DCV server from version 2022.2-14521 to 2023.0-15065.

Updating NICE DCV server

Figure 12: Updating NICE DCV server

Updating graphics drivers

You can use the download-<DRIVER_TYPE>-driver.cmd batch file to download the latest graphics driver for your instance type GPU. Downloaded files are located in the Downloads\Drivers folder.

Graphics driver download scripts

Figure 13: Graphics driver download scripts

AWS Command Line interface (AWS CLI v2) is installed in the instance. You can use it to view the different versions available on the driver S3 bucket. For example, the command aws s3 ls –recursive s3://nvidia-gaming/windows/ | sort /R lists NVIDIA gaming drivers available for download. NVIDIA GRID and AMD drivers are in the s3://ec2-windows-nvidia-drivers and s3://ec2-amd-windows-drivers S3 buckets respectively.

Listing graphics drivers on S3 bucket

Figure 14: Listing graphics drivers on S3 bucket

Use the command aws s3 cp s3://<S3_BUCKET_PATH>/<FILE-NAME>. to copy a specific driver from the S3 bucket to your local directory.

You can refer to Install NVIDIA drivers on Windows instances and Install AMD drivers on Windows instances for NVIDIA and AMD drivers installation instructions respectively.

Customizing your EC2 instance environment

You may want to customize the instance to your needs. For NVIDIA GPU instances, you can optimize GPU settings to achieve the best performance.

If you are doing video editing, then you can enable high color accuracy, configure multi-channel audio, and enable accurate audio/video sync. For gaming, you may enable gamepad support to use a DualShock 4 or Xbox 360 controller. NICE DCV session storage is enabled. This lets you transfer files using NICE DCV client. More configuration options are available from the NICE DCV User Guide and Administrator Guide.

Terminating your EC2 instance

When you have finished using your EC2 instance, you can release all provisioned resources by going to CloudFormation console to delete your stack.

Conclusion

The Amazon G4 and G5 GPU instance types are suitable for graphics-intensive applications, and NICE DCV provides a responsive and high image quality display protocol for remote access. Using the CloudFormation template from amazon-ec2-nice-dcv-samples GitHub site, you can build and maintain your own high performance Windows graphics workstation in the AWS cloud

New Amazon EC2 Instances (C7gd, M7gd, and R7gd) Powered by AWS Graviton3 Processor with Local NVMe-based SSD Storage

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/new-amazon-ec2-instances-c7gd-m7gd-and-r7gd-powered-by-aws-graviton3-processor-with-local-nvme-based-ssd-storage/

We launched Amazon EC2 C7g instances in May 2022 and M7g and R7g instances in February 2023. Powered by the latest AWS Graviton3 processors, the new instances deliver up to 25 percent higher performance, up to two times higher floating-point performance, and up to 2 times faster cryptographic workload performance compared to AWS Graviton2 processors.

Graviton3 processors deliver up to 3 times better performance compared to AWS Graviton2 processors for machine learning (ML) workloads, including support for bfloat16. They also support DDR5 memory that provides 50 percent more memory bandwidth compared to DDR4. Graviton3 also uses up to 60 percent less energy for the same performance as comparable EC2 instances, which helps you reduce your carbon footprint.

The C7g instances are well suited for compute-intensive workloads, such as high performance computing (HPC), batch processing, ad serving, video encoding, gaming, scientific modeling, distributed analytics, and CPU-based machine learning inference. The M7g instances are for general purpose workloads such as application servers, microservices, gaming servers, mid-sized data stores, and caching fleets. The R7g instances are a great fit for memory-intensive workloads such as open-source databases, in-memory caches, and real-time big data analytics.

Today, we’re adding a d variant to all three instance families. The new Amazon EC2 C7gd, M7gd, and R7gd instance types have NVM Express (NVMe) locally attached up to 2 x 1.9 TB SSD drives that are physically connected to the host server and provide block-level storage that is coupled to the lifetime of the instance. These instances have up to 45 percent better real-time NVMe storage performance than comparable Graviton2-based instances.

These are a great fit for applications that need access to high-speed, low-latency local storage, including those that need temporary storage of data for scratch space, temporary files, and caches. The data on an instance store volume persists only during the life of the associated EC2 instance.

Here are the specs for these instances:

Instance Size vCPU Memory
(GiB)
Local NVMe Storage (GB) Network Bandwidth
(Gbps)
EBS Bandwidth
(Gbps)
C7gd/M7gd/R7gd C7gd/M7gd/R7gd C7gd/M7gd/R7gd
medium 1 2/ 4 / 8 1 x 59 Up to 12.5 Up to 10
large 2 4 / 8 / 16 1 x 118 Up to 12.5 Up to 10
xlarge 4 8 / 16 / 32 1 x 237 Up to 12.5 Up to 10
2xlarge 8 16 / 32 / 64 1 x 474 Up to 15 Up to 10
4xlarge 16 32 / 64 / 128 1 x 950 Up to 15 Up to 10
8xlarge 32 64 / 128 / 256 1 x 1900 15 10
12xlarge 48 96 / 192/ 384 2 x 1425 22.5 15
16xlarge 64 128 / 256 / 512 2 x 1900 30 20

These instances are built on the AWS Nitro System, a combination of AWS-designed dedicated hardware and a lightweight hypervisor that allows the delivery of isolated multitenancy, private networking, and fast local storage. They provide up to 20 Gbps Amazon Elastic Block Store (Amazon EBS) bandwidth and up to 30 Gbps network bandwidth. The 16xlarge instances also support Elastic Fabric Adapter (EFA) for applications that need a high level of inter-node communication.

Now Available
Amazon EC2 C7gd, M7gd, and R7gd instances are now available in the following AWS Regions: US East (Ohio), US East (N. Virginia), US West (Oregon), and Europe (Ireland). As usual with Amazon EC2, you only pay for what you use. For more information, see the Amazon EC2 pricing page.

If you’re optimizing applications for Arm architecture, be sure to have a look at our Getting Started collection of resources or learn more about AWS Graviton3-based EC2 instances.

To learn more, visit our Amazon EC2 C7g instances, M7g instances or R7g instances page, and please send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

Channy

New – Amazon EC2 Hpc7g Instances Powered by AWS Graviton3E Processors Optimized for High Performance Computing Workloads

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/new-amazon-ec2-hpc7g-instances-powered-by-aws-graviton3e-processors-optimized-for-high-performance-computing-workloads/

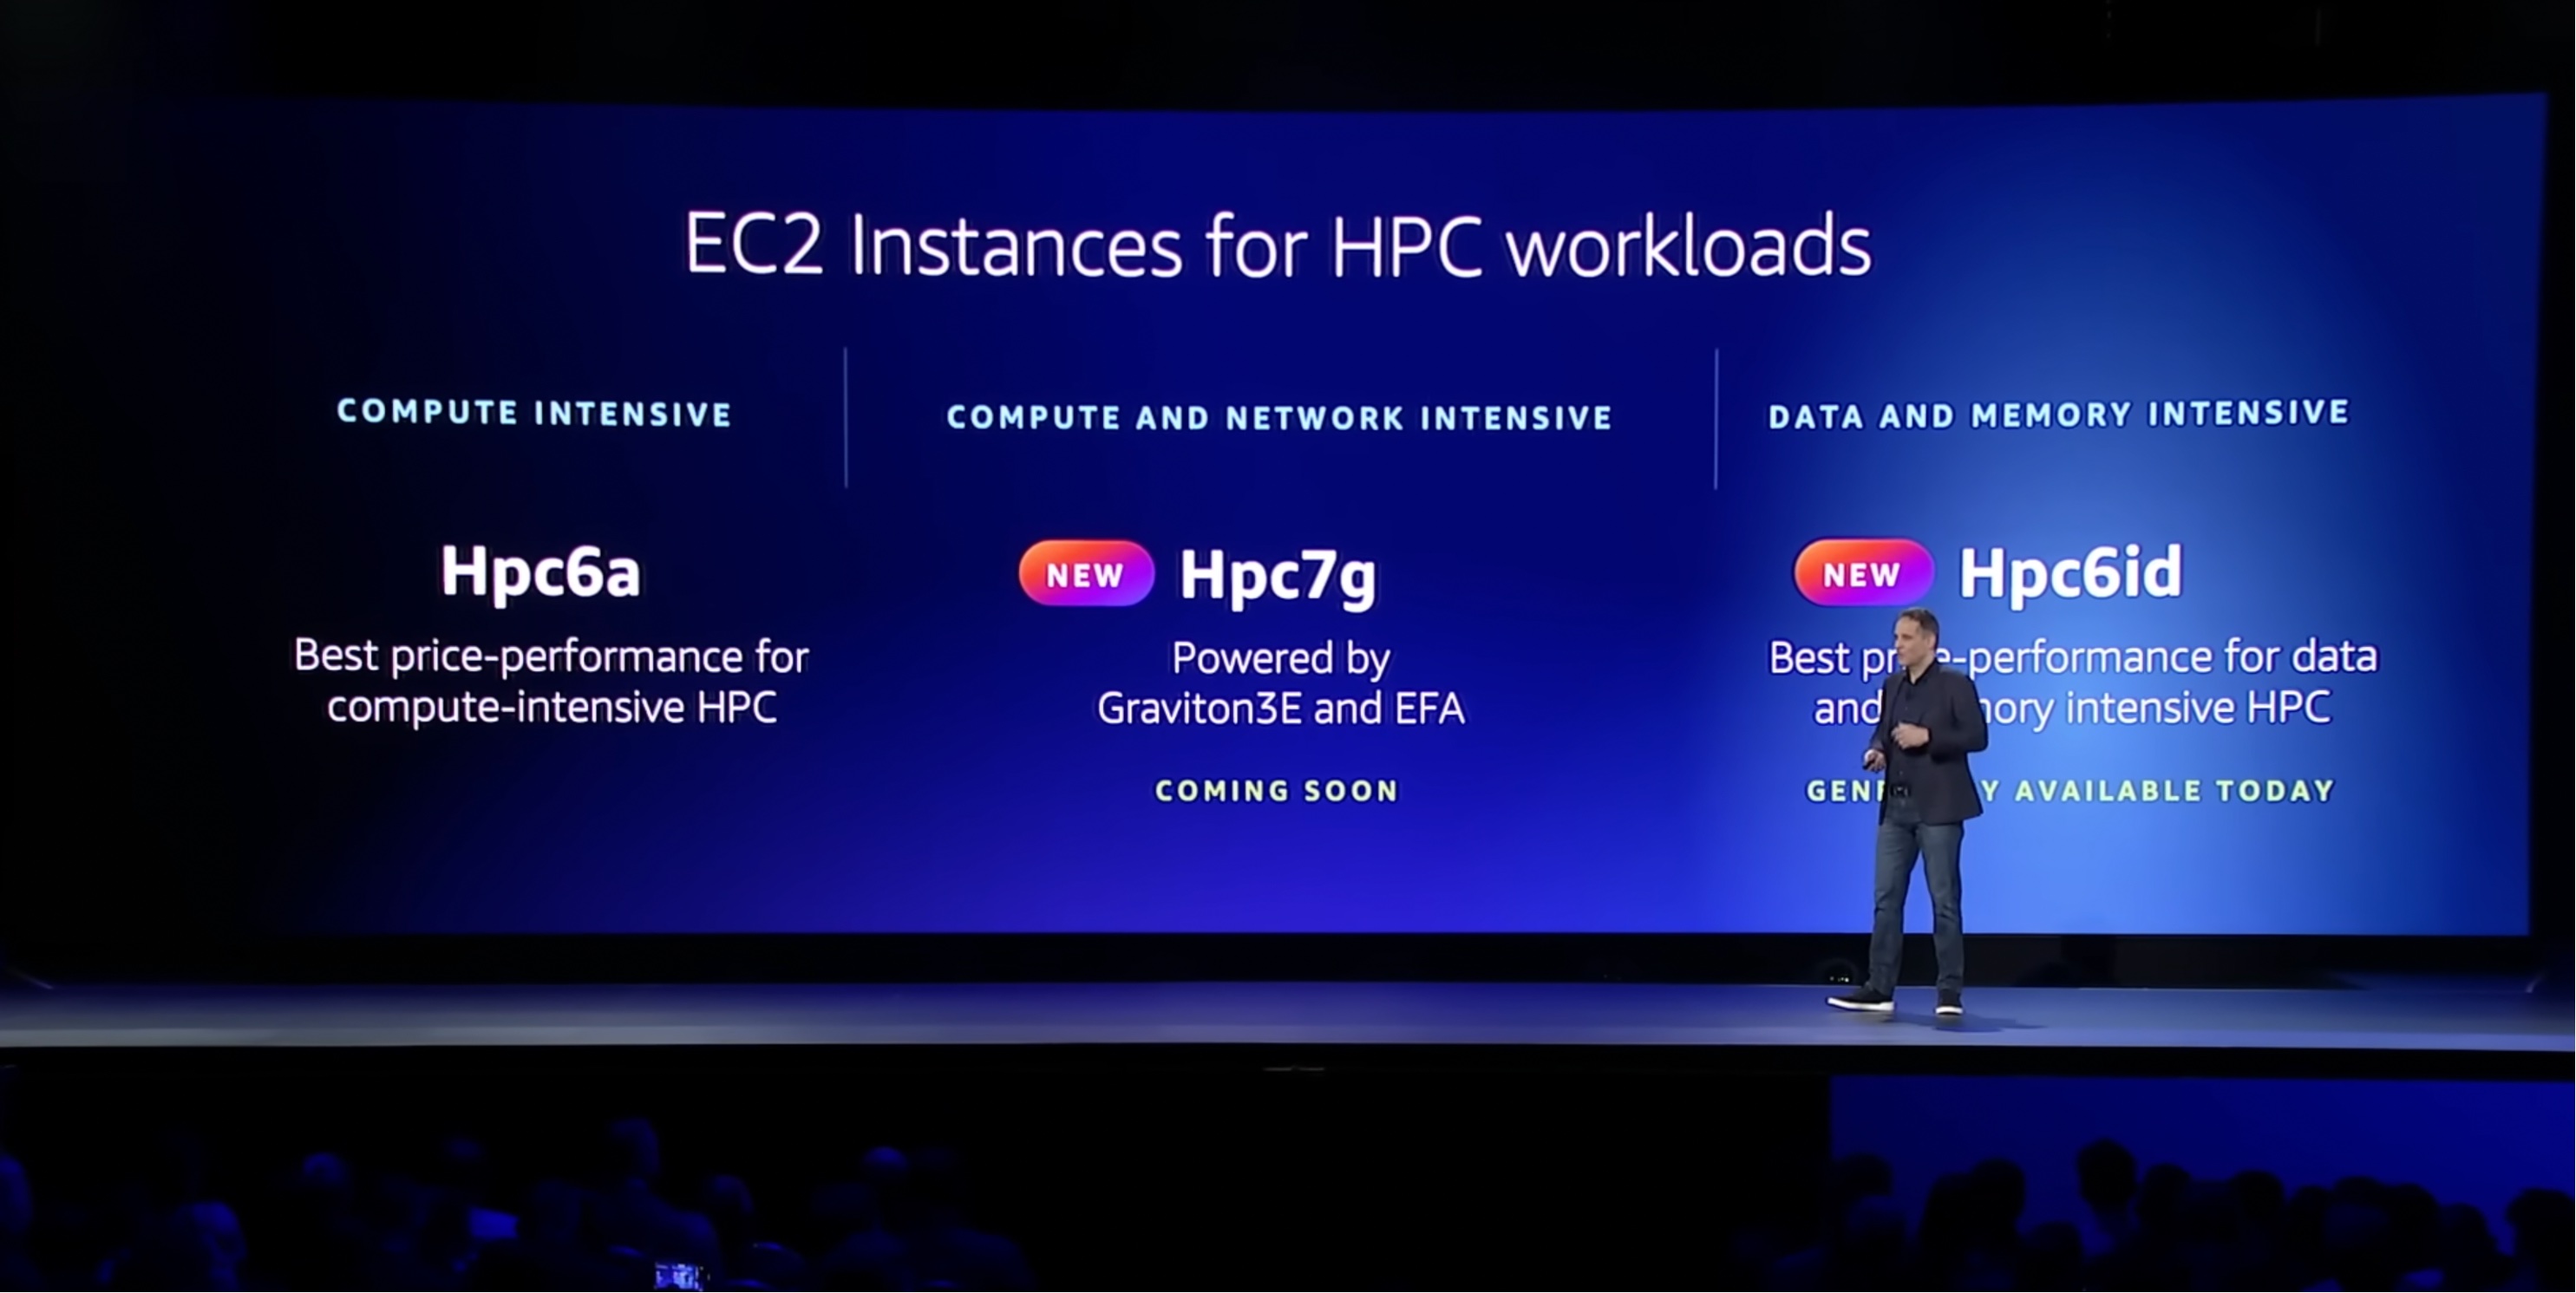
At AWS re:Invent 2022, Adam Selipsky, CEO of AWS, explained high performance computing (HPC) workloads typically can either be compute-intensive, compute- and networking-intensive, or data- and memory-intensive in his keynote.

Compute workloads include weather forecasting, computational fluid dynamics, and financial options pricing. To help with this, you have Amazon EC2 Hpc6a instances, which deliver up to 65 percent better price performance over comparable compute optimized x86-based instances.

Other HPC workloads require modeling the performance of complex structures—things like wind turbines, concrete buildings, and industrial equipment. Without enough data and memory, these models can take days or weeks to run in a cost-effective way. The Amazon EC2 Hpc6id instance is designed to deliver leading price performance for data and memory-intensive HPC workloads with higher memory bandwidth per core, faster local solid-state drive (SSD) storage, and enhanced networking with Elastic Fabric Adapter (EFA).

Announcing Amazon EC2 Hpc7g Instances
Compute-intensive HPC workloads such as weather forecasting, computational fluid dynamics, and financial options pricing also require more network performance, even better price performance, and greater energy efficiency.

Today we are announcing the general availability of Amazon EC2 Hpc7g instances, a new purpose-built instance type for tightly coupled compute and network-intensive HPC workloads.

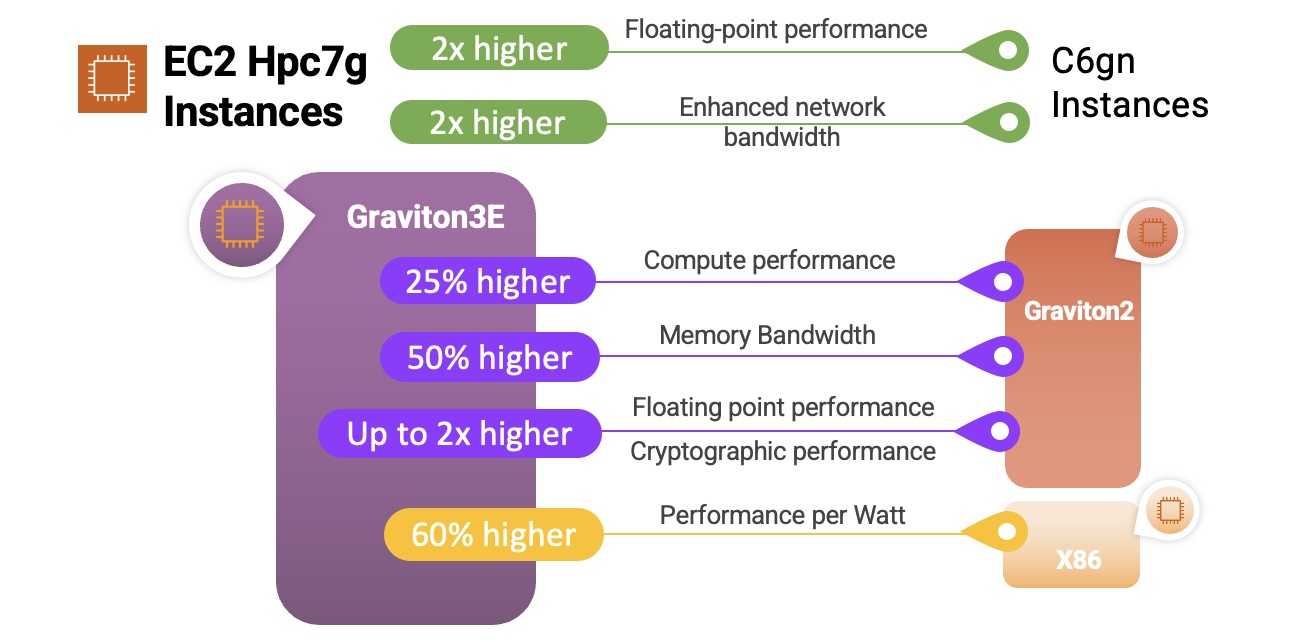
Hpc7g instances are powered by AWS Graviton3E processors that provide up to two times better floating-point performance and 200 Gbps dedicated EFA bandwidth than EC2 C6gn instances powered by AWS Graviton2 processors and are up to 60 percent more energy efficient than comparable x86 instances.

Here’s a quick infographic that shows you how the Hpc7g instances and the Graviton3E processors compare to previous instances and processors:

Hpc7g instances feature sizes of up to 64 cores of the latest AWS custom Graviton3E CPUs with 128 GiB RAM. Here are the detailed specs:

Instance Name
CPUs RAM (GiB)
EFA Network Bandwidth (Gbps) Attached Storage
hpc7g.4xlarge 16 128 Up to 200 EBS Only
hpc7g.8xlarge 32 128 Up to 200 EBS Only
hpc7g.16xlarge 64 128 Up to 200 EBS Only

Hpc7g instances are the most cost-efficient option to scale your HPC clusters on AWS. If you are considering migrating your largest HPC workloads requiring tens of thousands of cores at scale to AWS, you can take advantage of up to 200 Gbps EFA bandwidth to reduce the latency and run message passing interface (MPI) applications on parallel computing architectures while ensuring minimized power consumption on Hpc7g instances.

You can choose to use smaller sizes of Hpc7g instances to pick a lower number of cores and evenly distribute memory and network resources across the remaining cores to increase per-core performance to help reduce software licensing costs.

You can also use Hpc7g instances with AWS ParallelCluster to offer a complete HPC run-time environment that spans both x86 and arm64 instance types, giving you the flexibility to run different workload types within the same HPC cluster. You can compare and contrast performance, thus making it easier to find out what’s best for you and enabling easier porting of your workload.

Customer Story
The Water Institute is an independent, non-profit applied research organization that works across disciplines to advance science and develop integrated methods used to solve complex environmental and societal challenges.

They benchmarked the Hpc7g instances with 200 Gbps EFA using the Advanced Circulation (ADCIRC) model. ADCIRC is deployed throughout many US government agencies to simulate the movement of water due to astronomic tides, riverine flows, and atmospheric forces, including hurricanes and it is often used for real-time forecasting applications and design studies.

The model run for this application is targeted at Southern Louisiana and is the basis for most of the analysis conducted there including levee design, planning studies, and real-time hurricane storm surge forecasting applications. The left graphic above shows the full extent of the domain, while to the right of that, the high-resolution area targeted at Southern Louisiana shows flooding around the levees in New Orleans during a simulation of Hurricane Katrina.

The model contains 1.6 million vertices and 3 million elements. It’s these parameters that affect the computational complexity of the simulations. The simulations depict 18 days of astronomic tide, river inflows, and atmospheric wind and pressure forcing.

The Water Institute benchmarked against many of the instance types that would be useful for their workload types at AWS, including c6gn.16xlarge, hpc7g.16xlarge, hpc6a.48xlarge, and hpc6id.36xlarge.

The Hpc7g instance shows more than 40 percent better performance than the C6gn instance and has comparable performance to other high performance x86 instance types but with a better price-to-performance ratio. With Hpc7g instances, the Water Institute can lower its costs while maintaining the performance levels they expect.

RIKEN, who has built the powerful supercomputer, FUGAKU using arm64, is collaborating with AWS to create a virtual Fugaku using Hpc7g with Graviton3E to support Japanese manufacturers’ increasing demand for compute power. RIKEN has already confirmed that multiple Fugaku applications provide excellent performance on the AWS Graviton3E processor in the AWS cloud environment.

Also, Siemens has optimized the scalability of Simcenter STAR-CCM+ across a broad range of CPU and GPU instances on AWS. This technology is supported on Linux and available through Arm-based EC2 instances or the Fugaku supercomputer.

To hear more voices of customers and partners such as Ansys, Arup, CERFACS, ESI, Jij, ParTec, Rescale, and TotalCAE, see the Hpc7g instances page.

Now Available
Amazon EC2 Hpc7g instances are now generally available in the US East (N. Virginia) Region for purchase in On-Demand, Reserved Instance, and Savings Plan form.

To learn more, see the Amazon EC2 Hpc7g instances page. Give it a try, and please send feedback to AWS re:Post for High Performance Compute or through your usual AWS support contacts.

Channy

Deploying an automated Amazon CloudWatch dashboard for AWS Outposts using AWS CDK

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/deploying-an-automated-amazon-cloudwatch-dashboard-for-aws-outposts-using-aws-cdk/

This post is written by Enrico Liguori, Networking Solutions Architect, Hybrid Cloud and Sumeeth Siriyur, Sr. Hybrid Cloud Solutions Architect.

AWS Outposts is a fully managed service that brings the same AWS infrastructure, services, APIs, and tools to virtually any data center, colocation space, manufacturing floor, or on-premises facility where it might be needed. With Outposts, you can run some AWS services on-premises and connect to a broad range of services available in the local AWS Region. Outposts supports workloads requiring low latency, local data processing, data residency, and application migration.

Outposts capacity is driven as per your compute and storage requirements to run workloads. You can monitor Outposts resources using metrics gathered by Amazon CloudWatch. Using these metrics, you can effectively monitor and manage the Outposts resources as they would in the Region, levereging cloud native tools such as CloudWatch dashboards. Check the Monitoring best practices for AWS Outposts blog post to dive deep into the available monitoring options for Outposts.

CloudWatch dashboards are customizable home pages in the CloudWatch console that can be used to monitor resources running on Outposts in a single view. For example, you can monitor in a single pane the number Amazon EC2 instances used per EC2 instance type, the available capacity of Amazon EBS volumes and Amazon S3 buckets, and the operational status of the service link of Outposts.

As a you start deploying additional Outposts resources as a part of their capacity expansion, they must all be integrated and visualized within CloudWatch in an automated way. Traditionally CloudWatch dashboards are built manually and may be time consuming to tune. This post provides also an overview of building CloudWatch dashboards in an automated way using AWS Cloud Development Kit (AWS CDK).

Overview

CloudWatch metrics available to monitor Outposts resources and capacity

CloudWatch metrics for Outposts are available to customers in all public AWS Regions and AWS GovCloud (US) at no additional cost. We can classify the available metrics in two main categories:

To identify the metrics published under the service specific namespaces, we can leverage metadata in the form of tags. A tag is a label that you assign to an AWS resource and consists of a key and an optional value. For the purpose of the monitoring strategy described in this post, we use a tag that contains the OutpostID of the Outpost where the resource is deployed. In this way, we can easily filter the CloudWatch metrics that we would like to show in our dashboard.

To enforce the assignment of tags to our resources we can implement a tagging strategy using AWS tag Policies and Service Control Policies (SCPs).

The following sections describe two different methods to build a CloudWatch dashboard that includes the different types of metrics described so far. In both cases, we see how particularly useful the presence of tags is to identify the service-specific metrics.

Manual approach to building a CloudWatch dashboard for Outposts

This section describes a manual (i.e., non-automated) approach to building a dashboard that could summarize both the capacity utilization metrics and the service specific metrics for your resources running on Outposts.

The benefit of this approach is that we can implement a fully operational dashboard directly from the CloudWatch console. However, it will simultaneously require more effort to properly tune the dashboard to satisfy your monitoring requirements.

You can start creating the dashboard opening the CloudWatch console and following the steps listed in the public documentation.

To display a metric under AWS/Outposts namespace we can choose any of the widgets available. Based on the nature of the data, we can choose different types of Widgets such as Number, Line, Gauge, Explorer, or you can even build your own custom widget.

Together with the Widget type, we must select Outposts namespace in the metric graph dialog box and then navigate to the specific metric of interest.

In case we are creating the dashboard in a different account than the Outposts owner, we must select the right account in the View data drop-down menu to see the Outposts metric in which we are interested.

View data drop-down menu

After selecting one or more metrics we can select Create widget button.

For the service specific metrics, we recommend using the explorer widget. In this way, we can utilize the tagging strategy described earlier to automatically identify the metrics belonging to the resources running on Outposts. Check the documentation page for a step-by-step guide for creating an explorer widget based on tags.

Automated outpost dashboard

After we’ve seen how to build a dashboard manually from the console, in this secton we describe an automated approach to deploy a dashboard for Outposts through AWS CDK.

AWS CDK is an open source software development framework to model and provision your cloud application resources using familiar programming languages, including TypeScript, JavaScript, Python, C#, and Java. For the solution in this post, we use Python.

Architecture overview

The AWS CDK stack described in this post, assumes that the resources running on Outposts (EC2 instances, S3 buckets, Application Load Balancers (ALBs), and RDS instances) are tagged using the tagging strategy described earlier.

Specifying a tag name and a tag value in a configuration file automatically discovers the resources with that tag and adds the related metrics to the CloudWatch dashboard.

Together with the service specific metrics, it creates a series of widgets that we can use to monitor the capacity available and utilized in each Outpost that belongs to the account where the script is running.

The workflow is made of the following phases:

  1. The AWS CDK stack creates an AWS CodeCommit repository and uploads its own code into it. The code contains a series of modules, one for each section of the CloudWatch dashboard. A section of the dashboard contains one or more widgets showing the metrics of a specific service.
  2. To maintain the CloudWatch dashboard always up-to-date with the resources matching the tag, it creates a pipeline in AWS CodePipeline that can dynamically create and or update the dashboard. The pipeline runs the code in the CodeCommit repository and is made of two stages. In the first one, the build stage, it builds the dependencies needed by the AWS CDK stack. In the second stage, the Deploy stage, it loads and runs the modules used to build the dashboard.
  3. Each module contains the code to automatically discover the tagged resources of a specific service. This discovery phase uses standard AWS APIs called through the Python SDK Boto3.
  4. Based on the results of the discovery phase, AWS CDK produces an AWS CloudFormation template containing the definition of the CloudWatch dashboard sections. The template is submitted to CloudFormation.
  5. CloudFormation creates or, if already defined, updates the CloudWatch dashboard.
  6. Together with the dashboard, the AWS CDK script also contains the definition of a CloudWatch Event that, once deployed, triggers the pipeline each time a resource tagged with the specified tag is created or destroyed.

Prerequisites

To implement the solution presented in this post, you must configure:

  1. git as distributed version control system.
  2. In case it is the first time that you’re using AWS CDK in this account and region, you must:

a. Install the AWS CDK, and its prerequisites, following these instructions.

b. Go through the AWS CDK bootstrapping process. This is required only for the first time that we use AWS CDK in a specific AWS environment (an AWS environment is a combination of an AWS account and Region).

How to install

Step 1: Clone the AWS CDK code hosted on GitHub with:

$ git clone https://github.com/aws-samples/automated-cloudwatch-dashboard.git

Step 2: enter the directory using the following:

$ cd  automated-cloudwatch-dashboard/

Step 3: Install the needed Python dependencies with:

$ pip install -r requirements.txt

Step 4: Modify the configuration file

Before deploying the stack, we must modify the configuration file to specify the tag we use for identifying our resources running on Outposts. Open the file with the name config.yaml with your preferred text editor and specify:

      • A name for the dashboard. The default name used is Automated-CloudWatch-Dashboard.
      • Replace <tag_name> placeholder following the tag_name variable with the tag name used to tag the resources that you want to include in the dashboard.
      • Replace <tag_value> placeholder under tag_values variable with the tag value that you used.

Here is an example config.yaml configuration file:

dashboard_name: Automated-CloudWatch-Dahsboard
tag_name: OutpostID
tag_values:
  - op-1234567890abcdefg 

Stack deployment

We can deploy the stack with the following:

$ cdk deploy

At the end of the deployment process, the pipeline that creates the dashboard is provisioned. You can now go to your CloudWatch console to view it.

Automated Outposts dashboard overview

Now that we have built our dashboard, let’s review each section:

  1. Outpost capacity

Outpost Capacity diagram

The AWS CDK stacks define a capacity section for each Outpost available to the AWS account where the script runs.

In this section, we find four widgets showing metrics published under the AWS/Outpost namespace. The first widget shows for each EC2 instance type available on the Outposts the number of instances utilized and available for that instance type. In the second row, we can visualize the available capacity for the Amazon EBS volumes and for the S3 buckets. The last widget shows the operational status of the service link of Outposts.

2. EC2 instances

CPU, Network, and Disk Utilization for an EC2 instance diagram

In this section of the dashboard, we find the metrics showing the CPU, Network, and Disk Utilization for an EC2 instance. It has defined a section of this type for each EC2 instance with a tag assigned matching the name and the value specified in the configuration file of the script.

3. Application Load Balancer

The ALB section aggregates metrics showing the operational status of a load balancer hosted on Outposts

The ALB section aggregates metrics showing the operational status of a load balancer hosted on Outposts. A section of this type is defined for each ALB with an assigned tag matching the one specified in the configuration file.

4. S3 buckets

The S3 buckets section diagram

The S3 buckets section is defined only once and aggregates the utilization metrics for all S3 buckets with an assigned tag.

5. AutoScaling group

The AutoScaling group section diagram

The AutoScaling group section can be used to monitor the number of instances in service in a specific AS group with a tag assigned. This section is defined once and can aggregate the metrics for multiple AutoScaling groups.

Clean up

To terminate the resources that we created in this post, run the following:

$ cdk destroy

Then, go to the Cloudformation console and delete the stack with the name “Deploy-AutomatedCloudWatchDashboard”.

Conclusion

In conclusion, this post demonstrates a manual way of creating CloudWatch Metrics dashboard using the CloudWatch console and an automated way using AWS CDK. The automated approach is also scalable by automatically discovering any new resources added to the existing Outposts in the your environment without any changes to the code.

Secure Connectivity from Public to Private: Introducing EC2 Instance Connect Endpoint

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/secure-connectivity-from-public-to-private-introducing-ec2-instance-connect-endpoint-june-13-2023/

This blog post is written by Ariana Rahgozar, Solutions Architect, and Kenneth Kitts, Sr. Technical Account Manager, AWS.

Imagine trying to connect to an Amazon Elastic Compute Cloud (Amazon EC2) instance within your Amazon Virtual Private Cloud (Amazon VPC) over the Internet. Typically, you’d first have to connect to a bastion host with a public IP address that your administrator set up over an Internet Gateway (IGW) in your VPC, and then use port forwarding to reach your destination.

Today we launched Amazon EC2 Instance Connect (EIC) Endpoint, a new feature that allows you to connect securely to your instances and other VPC resources from the Internet. With EIC Endpoint, you no longer need an IGW in your VPC, a public IP address on your resource, a bastion host, or any agent to connect to your resources. EIC Endpoint combines identity-based and network-based access controls, providing the isolation, control, and logging needed to meet your organization’s security requirements. As a bonus, your organization administrator is also relieved of the operational overhead of maintaining and patching bastion hosts for connectivity. EIC Endpoint works with the AWS Management Console and AWS Command Line Interface (AWS CLI). Furthermore, it gives you the flexibility to continue using your favorite tools, such as PuTTY and OpenSSH.

In this post, we provide an overview of how the EIC Endpoint works and its security controls, guide you through your first EIC Endpoint creation, and demonstrate how to SSH to an instance from the Internet over the EIC Endpoint.

EIC Endpoint product overview

EIC Endpoint is an identity-aware TCP proxy. It has two modes: first, AWS CLI client is used to create a secure, WebSocket tunnel from your workstation to the endpoint with your AWS Identity and Access Management (IAM) credentials. Once you’ve established a tunnel, you point your preferred client at your loopback address (127.0.0.1 or localhost) and connect as usual. Second, when not using the AWS CLI, the Console gives you secure and seamless access to resources inside your VPC. Authentication and authorization is evaluated before traffic reaches the VPC. The following figure shows an illustration of a user connecting via an EIC Endpoint:

Figure 1 shows a user connecting to private EC2 instances within a VPC through an EIC Endpoint

Figure 1. User connecting to private EC2 instances through an EIC Endpoint

EIC Endpoints provide a high degree of flexibility. First, they don’t require your VPC to have direct Internet connectivity using an IGW or NAT Gateway. Second, no agent is needed on the resource you wish to connect to, allowing for easy remote administration of resources which may not support agents, like third-party appliances. Third, they preserve existing workflows, enabling you to continue using your preferred client software on your local workstation to connect and manage your resources. And finally, IAM and Security Groups can be used to control access, which we discuss in more detail in the next section.

Prior to the launch of EIC Endpoints, AWS offered two key services to help manage access from public address space into a VPC more carefully. First is EC2 Instance Connect, which provides a mechanism that uses IAM credentials to push ephemeral SSH keys to an instance, making long-lived keys unnecessary. However, until now EC2 Instance Connect required a public IP address on your instance when connecting over the Internet. With this launch, you can use EC2 Instance Connect with EIC Endpoints, combining the two capabilities to give you ephemeral-key-based SSH to your instances without exposure to the public Internet. As an alternative to EC2 Instance Connect and EIC Endpoint based connectivity, AWS also offers Systems Manager Session Manager (SSM), which provides agent-based connectivity to instances. SSM uses IAM for authentication and authorization, and is ideal for environments where an agent can be configured to run.

Given that EIC Endpoint enables access to private resources from public IP space, let’s review the security controls and capabilities in more detail before discussing creating your first EIC Endpoint.

Security capabilities and controls

Many AWS customers remotely managing resources inside their VPCs from the Internet still use either public IP addresses on the relevant resources, or at best a bastion host approach combined with long-lived SSH keys. Using public IPs can be locked down somewhat using IGW routes and/or security groups. However, in a dynamic environment those controls can be hard to manage. As a result, careful management of long-lived SSH keys remains the only layer of defense, which isn’t great since we all know that these controls sometimes fail, and so defense-in-depth is important. Although bastion hosts can help, they increase the operational overhead of managing, patching, and maintaining infrastructure significantly.

IAM authorization is required to create the EIC Endpoint and also to establish a connection via the endpoint’s secure tunneling technology. Along with identity-based access controls governing who, how, when, and how long users can connect, more traditional network access controls like security groups can also be used. Security groups associated with your VPC resources can be used to grant/deny access. Whether it’s IAM policies or security groups, the default behavior is to deny traffic unless it is explicitly allowed.

EIC Endpoint meets important security requirements in terms of separation of privileges for the control plane and data plane. An administrator with full EC2 IAM privileges can create and control EIC Endpoints (the control plane). However, they cannot use those endpoints without also having EC2 Instance Connect IAM privileges (the data plane). Conversely, DevOps engineers who may need to use EIC Endpoint to tunnel into VPC resources do not require control-plane privileges to do so. In all cases, IAM principals using an EIC Endpoint must be part of the same AWS account (either directly or by cross-account role assumption). Security administrators and auditors have a centralized view of endpoint activity as all API calls for configuring and connecting via the EIC Endpoint API are recorded in AWS CloudTrail. Records of data-plane connections include the IAM principal making the request, their source IP address, the requested destination IP address, and the destination port. See the following figure for an example CloudTrail entry.

Figure 2 shows a sample cloud trail entry for SSH data-plane connection for an IAMUser. Specific entry:  Figure 2. Partial CloudTrail entry for an SSH data-plane connection

EIC Endpoint supports the optional use of Client IP Preservation (a.k.a Source IP Preservation), which is an important security consideration for certain organizations. For example, suppose the resource you are connecting to has network access controls that are scoped to your specific public IP address, or your instance access logs must contain the client’s “true” IP address. Although you may choose to enable this feature when you create an endpoint, the default setting is off. When off, connections proxied through the endpoint use the endpoint’s private IP address in the network packets’ source IP field. This default behavior allows connections proxied through the endpoint to reach as far as your route tables permit. Remember, no matter how you configure this setting, CloudTrail records the client’s true IP address.

EIC Endpoints strengthen security by combining identity-based authentication and authorization with traditional network-perimeter controls and provides for fine-grained access control, logging, monitoring, and more defense in depth. Moreover, it does all this without requiring Internet-enabling infrastructure in your VPC, minimizing the possibility of unintended access to private VPC resources.

Getting started

Creating your EIC Endpoint

Only one endpoint is required per VPC. To create or modify an endpoint and connect to a resource, a user must have the required IAM permissions, and any security groups associated with your VPC resources must have a rule to allow connectivity. Refer to the following resources for more details on configuring security groups and sample IAM permissions.

The AWS CLI or Console can be used to create an EIC Endpoint, and we demonstrate the AWS CLI in the following. To create an EIC Endpoint using the Console, refer to the documentation.

Creating an EIC Endpoint with the AWS CLI

To create an EIC Endpoint with the AWS CLI, run the following command, replacing [SUBNET] with your subnet ID and [SG-ID] with your security group ID:

aws ec2 create-instance-connect-endpoint \
    --subnet-id [SUBNET] \
    --security-group-id [SG-ID]

After creating an EIC Endpoint using the AWS CLI or Console, and granting the user IAM permission to create a tunnel, a connection can be established. Now we discuss how to connect to Linux instances using SSH. However, note that you can also use the OpenTunnel API to connect to instances via RDP.

Connecting to your Linux Instance using SSH

With your EIC Endpoint set up in your VPC subnet, you can connect using SSH. Traditionally, access to an EC2 instance using SSH was controlled by key pairs and network access controls. With EIC Endpoint, an additional layer of control is enabled through IAM policy, leading to an enhanced security posture for remote access. We describe two methods to connect via SSH in the following.

One-click command

To further reduce the operational burden of creating and rotating SSH keys, you can use the new ec2-instance-connect ssh command from the AWS CLI. With this new command, we generate ephemeral keys for you to connect to your instance. Note that this command requires use of the OpenSSH client. To use this command and connect, you need IAM permissions as detailed here.

Once configured, you can connect using the new AWS CLI command, shown in the following figure:
Figure 3 shows the AWS CLI view if successfully connecting to your instance using the one-click command. When running the command, you are prompted to connect and can access your instance.

Figure 3. AWS CLI view upon successful SSH connection to your instance

To test connecting to your instance from the AWS CLI, you can run the following command where [INSTANCE] is the instance ID of your EC2 instance:

aws ec2-instance-connect ssh --instance-id [INSTANCE]

Note that you can still use long-lived SSH credentials to connect if you must maintain existing workflows, which we will show in the following. However, note that dynamic, frequently rotated credentials are generally safer.

Open-tunnel command

You can also connect using SSH with standard tooling or using the proxy command. To establish a private tunnel (TCP proxy) to the instance, you must run one AWS CLI command, which you can see in the following figure:

Figure 4 shows the AWS CLI view after running the aws ec2-instance-connect open-tunnel command and connecting to your instance.Figure 4. AWS CLI view after running new SSH open-tunnel command, creating a private tunnel to connect to our EC2 instance

You can run the following command to test connectivity, where [INSTANCE] is the instance ID of your EC2 instance and [SSH-KEY] is the location and name of your SSH key. For guidance on the use of SSH keys, refer to our documentation on Amazon EC2 key pairs and Linux instances.

ssh ec2-user@[INSTANCE] \
    -i [SSH-KEY] \
    -o ProxyCommand='aws ec2-instance-connect open-tunnel \
    --instance-id %h'

Once we have our EIC Endpoint configured, we can SSH into our EC2 instances without a public IP or IGW using the AWS CLI.

Conclusion

EIC Endpoint provides a secure solution to connect to your instances via SSH or RDP in private subnets without IGWs, public IPs, agents, and bastion hosts. By configuring an EIC Endpoint for your VPC, you can securely connect using your existing client tools or the Console/AWS CLI. To learn more, visit the EIC Endpoint documentation.

AWS Week in Review – Automate DLQ Redrive for SQS, Lambda Supports Ruby 3.2, and More – June 12, 2023

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/aws/aws-week-in-review-automate-dlq-redrive-for-sqs-lambda-supports-ruby-3-2-and-more-june-12-2023/

Today I’m boarding a plane for Madrid. I will attend the AWS Summit Madrid this Thursday, and I will take Serverlesspresso with me. Serverlesspresso is a demo that we take to events, in where you can learn how to build event-driven architectures with serverless. If you are visiting an AWS Summit, most probably you will find one of our booths.

Serverlesspresso at Madrid

Last Week’s Launches
Here are some launches that got my attention during the previous week.

Amazon SQS – Customers were very excited when we announced the DLQ redrive for Amazon SQS as that feature helped them to easily redirect the failed messages. This week we added support for AWS SDK and CLI for this feature, allowing you to redrive the messages on the DLQ automatically, making it even easier to use this feature. You can read Seb’s blog post about this new feature to learn how to get started.

AWS Lambda – AWS Lambda now supports Ruby 3.2. Ruby 3.2 has many new improvements, for example, passing anonymous arguments to functions or having endless methods. Check out this blog post that goes in depth into each of the new features.

Amazon Fraud DetectorAmazon Fraud Detector supports event orchestration with Amazon EventBridge. This is a very important feature because now you can act on the different events that Fraud Detector emits, for example, send notifications to different stakeholders.

AWS Glue – This week, AWS Glue made two important announcements. First, it announced the general availability of AWS Glue for Ray, a new data integration engine option for AWS Glue. Ray is a popular new open-source compute framework that helps developers to scale their Python workloads. In addition, AWS Glue announced AWS Glue Data Quality, a new capability that automatically measures and monitors data lake and data pipeline quality.

Amazon Elastic Container Registry (Amazon ECR)AWS Signer and Amazon ECR announced a new feature that allows you to sign and verify container images. You can use Signer to validate that only container images you have approved are deployed in your Amazon Elastic Kubernetes Service (Amazon EKS) clusters.

Amazon QuickSightAmazon QuickSight now supports APIs to automate asset deployment, so you can replicate the same QuickSight assets in multiple Regions and account easily. You can read more on how to use those APIs in this blog post.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
Some other updates and news that you may have missed:

Upcoming AWS Events
Check your calendars and sign up for these AWS events:

  • AWS Silicon Innovation Day (June 21) – A one-day virtual event that focuses on AWS Silicon and how you can take advantage of AWS’s unique offerings. Learn more and register here.
  • AWS Global Summits – There are many summits going on right now around the world: Toronto (June 14), Madrid (June 15), and Milano (June 22).
  • AWS Community Day – Join a community-led conference run by AWS user group leaders in your region: Chicago (June 15), Manila (June 29–30), Chile (July 1), and Munich (September 14).
  • CDK Day CDK Day is happening again this year on September 29. The call for papers for this event is open, and this year we are also accepting talks in Spanish. Submit your talk here.

That’s all for this week. Check back next Monday for another Week in Review!

This post is part of our Week in Review series. Check back each week for a quick roundup of interesting news and announcements from AWS!

— Marcia

Selecting cost effective capacity reservations for your business-critical workloads on Amazon EC2

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/selecting-cost-effective-capacity-reservations-for-your-business-critical-workloads-on-amazon-ec2/

This blog post is written by Sarath Krishnan, Senior Solutions Architect and Navdeep Singh, Senior Customer Solutions Manager.

Amazon CTO Werner Vogels famously said, “everything fails all the time.” Designing your systems for failure is important for ensuring availability, scalability, fault tolerance and business continuity. Resilient systems scale with your business demand changes, prevent data loss, and allow for seamless recovery from failures. There are many strategies and architectural patterns to build resilient systems on AWS. Building resiliency often involves running duplicate workloads and maintaining backups and failover mechanisms. However, these additional resources may translate into higher costs. It is important to balance the cost of implementing resiliency measures against the potential cost of downtime and the associated risks to the organization.

In addition to the resilient architectural patterns, if your business-critical workloads are running on Amazon Elastic Compute Cloud (Amazon EC2) instances, it is imperative to understand different EC2 capacity reservation options available in AWS. Capacity reservations ensure that you always have access to Amazon EC2 capacity when you need it. For instance, Multi-AZ deployment is one of the architectural patterns to build highly resilient systems on AWS. In a Multi-AZ deployment, you spread your workload across multiple Availability Zones (AZs) with an Auto Scaling group. In an unlikely event of an AZ failure, the Auto Scaling group will try to bring up your instance in another AZ. In a rare scenario, the other AZ may not have the capacity at that time for your specific instance type, hence capacity reservations are important for your crucial workloads.

While implementing capacity reservations, it is important to understand how to control costs for your capacity reservations. In this post, we describe different EC2 capacity reservation and cost savings options available at AWS.

Amazon EC2 Purchase Options

Before we dive into the capacity reservation options, it is important to understand different EC2 instance purchase options available on AWS. EC2 On-Demand purchase option enables you to pay by the second for the instance you launch. Spot Instances purchase option allows you to request unused EC2 capacity for a steep discount. Savings Plans enable you to reduce cost through one- or three-year usage commitments.

Dedicated Hosts and Dedicated Instances allow you to run EC2 instances on single-tenant hardware. But only the On-Demand Capacity Reservations and zonal reservations can reserve capacity for your EC2 instances..

On-Demand Capacity Reservations Deep Dive

On-Demand Capacity Reservations enable you to reserve compute capacity for your Amazon EC2 instances in a specific AZ for any duration. On-Demand Capacity Reservations ensure On-Demand capacity allocation during capacity constraints without entering into a long-term commitment. With On-Demand Capacity Reservations, you pay on-demand price irrespective of your instance running or not. If your business needs capacity reservations only for a shorter duration, like a holiday season, or for a critical business event, such as large streaming event held once a quarter, On-Demand Capacity Reservations is the right fit for your needs. However, if you need capacity reservations for your business-critical workloads for a longer period consistently, we recommend combining On-Demand Capacity Reservations with Savings Plans to achieve capacity reservations and cost savings.

Savings Plans

Savings Plans is a flexible pricing model that can help you reduce your bill by up to 72% compared to On-Demand prices, in exchange for a one – or three-year hourly spend commitment. AWS offers three types of Savings Plans: Compute Savings Plans, EC2 Instance Savings Plans, and Amazon SageMaker Savings Plans.

With EC2 Instance Savings Plans, you can make an hourly spend commitment for instance family and region (e.g. M5 usage in N. Virginia) for one- or three-year terms. Savings are automatically applied to the instances launched in the selected instance family and region irrespective of size, tenancy and operating system. EC2 Instance Savings Plans also give you the flexibility to change your usage between instances within a family in that region. For example, you can move from c5.xlarge running Windows to c5.2xlarge running Linux and automatically benefit from the Savings Plans prices. EC2 Instance Savings Plans gets you the maximum discount of up to 72%.

Compute Savings Plans offer great flexibility as you can change the instance types, migrate workloads between regions, or move workloads to AWS Fargate or AWS Lambda and automatically continue to pay the discounted Savings Plans price. If you are an EC2 customer today, and planning to modernize your applications by leveraging AWS Fargate or AWS Lambda, evaluating Compute Savings Plans is recommended. This plan offers great flexibility so that your commercial agreements support your long-term changing architectural needs and offer cost savings of up to 66%. For example, with Compute Savings Plans, you can change from C4 to M5 instances, shift a workload from EU (Ireland) to EU (London), or move a workload from EC2 to Fargate or Lambda at any time and automatically continue to pay the Savings Plans price. Combining On-Demand Capacity Reservations with Compute Savings Plans give the capacity reservations, significant discounts and maximum flexibility.

We recommend utilizing Savings Plans for discounts due to its flexibility. However, some of the AWS customers might still have older Reserved Instances. If you have already purchased Reserved Instances and want to ensure capacity reservations, you can combine On-Demand Capacity Reservations with Reserved Instances to get the capacity reservations and the discounts. As your Reserved Instances expire, we recommend to sign up for Savings Plans as they offer the same savings as Reserved Instances, but with additional flexibility.

You may find Savings Plans pricing discount examples explained in the Savings Plans documentation.

Zonal Reservations

Zonal reservations offer reservation of capacity in a specific AZ. Zonal reservation requires one- or three- years commitment and reservation applies to a pre-defined instance family. Zonal reservation provides less flexibility as compared to Savings Plans. With zonal reservations, you do not have flexibility to change the instance family and its size. Zonal reservation also does not support queuing your purchase for a future date. We recommend to consider Savings Plans and On-Demand Capacity Reservations over zonal Reserved Instances so that you can get similar discounts and you get much better flexibility. If you are already on a zonal reservation, as your plan expires, we recommend you sign up for Savings Plans and On-Demand Capacity Reservations .

Working with Capacity Reservations and Savings Plans

You may provision capacity reservations using AWS console, Command Line Interface(CLI), and Application Programming Interface (API).

Work with capacity reservations documentation explains the steps to provision the On-Demand Capacity Reservations using AWS console and CLI in detail. You may find the steps to purchase the Savings Plans explained in the documentation.

Conclusion

In this post, we discussed different options for capacity reservations and cost control for your mission-critical workloads on EC2. For most flexibility and value, we recommend using On-Demand Capacity Reservations with Savings Plans. If you have a steady EC2 workloads which are not suitable candidates for modernization, EC2 Savings Plans is recommended. If you are looking for more flexibility of changing the instance types, migrate workloads between regions or planning to modernize your workloads leveraging AWS Fargate or AWS Lambda, consider Compute Savings Plans. Zonal reservations are not the preferred capacity reservation approach due to its lack of flexibility. If you need the capacity reservation for a short period of time, you may leverage the flexibility of On-Demand Capacity Reservations to book and cancel the reservations anytime.

You may refer to the blog to implement Reserving EC2 Capacity across Availability Zones by utilizing On Demand Capacity Reservations.

Reserving EC2 Capacity across Availability Zones by utilizing On Demand Capacity Reservations (ODCRs)

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/reserving-ec2-capacity-across-availability-zones-by-utilizing-on-demand-capacity-reservations-odcrs/

This post is written by Johan Hedlund, Senior Solutions Architect, Enterprise PUMA.

Many customers have successfully migrated business critical legacy workloads to AWS, utilizing services such as Amazon Elastic Compute Cloud (Amazon EC2), Auto Scaling Groups (ASGs), as well as the use of Multiple Availability Zones (AZs), Regions for Business Continuity, and High Availability.

These critical applications require increased levels of availability to meet strict business Service Level Agreements (SLAs), even in extreme scenarios such as when EC2 functionality is impaired (see Advanced Multi-AZ Resilience Patterns for examples). Following AWS best practices such as architecting for flexibility will help here, but for some more rigid designs there can still be challenges around EC2 instance availability.

In this post, I detail an approach for Reserving Capacity for this type of scenario to mitigate the risk of the instance type(s) that your application needs being unavailable, including code for building it and ways of testing it.

Baseline: Multi-AZ application with restrictive instance needs

To focus on the problem of Capacity Reservation, our reference architecture is a simple horizontally scalable monolith. This consists of a single executable running across multiple instances as a cluster in an Auto Scaling group across three AZs for High Availability.

Architecture diagram featuring an Auto Scaling Group spanning three Availability Zones within one Region for high availability.

The application in this example is both business critical and memory intensive. It needs six r6i.4xlarge instances to meet the required specifications. R6i has been chosen to meet the required memory to vCPU requirements.

The third-party application we need to run, has a significant license cost, so we want to optimize our workload to make sure we run only the minimally required number of instances for the shortest amount of time.

The application should be resilient to issues in a single AZ. In the case of multi-AZ impact, it should failover to Disaster Recovery (DR) in an alternate Region, where service level objectives are instituted to return operations to defined parameters. But this is outside the scope for this post.

The problem: capacity during AZ failover

In this solution, the Auto Scaling Group automatically balances its instances across the selected AZs, providing a layer of resilience in the event of a disruption in a single AZ. However, this hinges on those instances being available for use in the Amazon EC2 capacity pools. The criticality of our application comes with SLAs which dictate that even the very low likelihood of instance types being unavailable in AWS must be mitigated.

The solution: Reserving Capacity

There are 2 main ways of Reserving Capacity for this scenario: (a) Running extra capacity 24/7, (b) On Demand Capacity Reservations (ODCRs).

In the past, another recommendation would have been to utilize Zonal Reserved Instances (Non Zonal will not Reserve Capacity). But although Zonal Reserved Instances do provide similar functionality as On Demand Capacity Reservations combined with Savings Plans, they do so in a less flexible way. Therefore, the recommendation from AWS is now to instead use On Demand Capacity Reservations in combination with Savings Plans for scenarios where Capacity Reservation is required.

The TCO impact of the licensing situation rules out the first of the two valid options. Merely keeping the spare capacity up and running all the time also doesn’t cover the scenario in which an instance needs to be stopped and started, for example for maintenance or patching. Without Capacity Reservation, there is a theoretical possibility that that instance type would not be available to start up again.

This leads us to the second option: On Demand Capacity Reservations.

How much capacity to reserve?

Our failure scenario is when functionality in one AZ is impaired and the Auto Scaling Group must shift its instances to the remaining AZs while maintaining the total number of instances. With a minimum requirement of six instances, this means that we need 6/2 = 3 instances worth of Reserved Capacity in each AZ (as we can’t know in advance which one will be affected).

Illustration of number of instances required per Availability Zone, in order to keep the total number of instances at six when one Availability Zone is removed. When using three AZs there are two instances per AZ. When using two AZs there are three instances per AZ.

Spinning up the solution

If you want to get hands-on experience with On Demand Capacity Reservations, refer to this CloudFormation template and its accompanying README file for details on how to spin up the solution that we’re using. The README also contains more information about the Stack architecture. Upon successful creation, you have the following architecture running in your account.

Architecture diagram featuring adding a Resource Group of On Demand Capacity Reservations with 3 On Demand Capacity Reservations per Availability Zone.

Note that the default instance type for the AWS CloudFormation stack has been downgraded to t2.micro to keep our experiment within the AWS Free Tier.

Testing the solution

Now we have a fully functioning solution with Reserved Capacity dedicated to this specific Auto Scaling Group. However, we haven’t tested it yet.

The tests utilize the AWS Command Line Interface (AWS CLI), which we execute using AWS CloudShell.

To interact with the resources created by CloudFormation, we need some names and IDs that have been collected in the “Outputs” section of the stack. These can be accessed from the console in a tab under the Stack that you have created.

Example of outputs from running the CloudFormation stack. AutoScalingGroupName, SubnetForManuallyAddedInstance, and SubnetsToKeepWhenDroppingASGAZ.

We set these as variables for easy access later (replace the values with the values from your stack):

export AUTOSCALING_GROUP_NAME=ASGWithODCRs-CapacityBackedASG-13IZJWXF9QV8E
export SUBNET_FOR_MANUALLY_ADDED_INSTANCE=subnet-03045a72a6328ef72
export SUBNETS_TO_KEEP=subnet-03045a72a6328ef72,subnet-0fd00353b8a42f251

How does the solution react to scaling out the Auto Scaling Group beyond the Capacity Reservation?

First, let’s look at what happens if the Auto Scaling Group wants to Scale Out. Our requirements state that we should have a minimum of six instances running at any one time. But the solution should still adapt to increased load. Before knowing anything about how this works in AWS, imagine two scenarios:

  1. The Auto Scaling Group can scale out to a total of nine instances, as that’s how many On Demand Capacity Reservations we have. But it can’t go beyond that even if there is On Demand capacity available.
  2. The Auto Scaling Group can scale just as much as it could when On Demand Capacity Reservations weren’t used, and it continues to launch unreserved instances when the On Demand Capacity Reservations run out (assuming that capacity is in fact available, which is why we have the On Demand Capacity Reservations in the first place).

The instances section of the Amazon EC2 Management Console can be used to show our existing Capacity Reservations, as created by the CloudFormation stack.

Listing of consumed Capacity Reservations across the three Availability Zones, showing two used per Availability Zone.

As expected, this shows that we are currently using six out of our nine On Demand Capacity Reservations, with two in each AZ.

Now let’s scale out our Auto Scaling Group to 12, thus using up all On Demand Capacity Reservations in each AZ, as well as requesting one extra Instance per AZ.

aws autoscaling set-desired-capacity \
--auto-scaling-group-name $AUTOSCALING_GROUP_NAME \
--desired-capacity 12

The Auto Scaling Group now has the desired Capacity of 12:

Group details of the Auto Scaling Group, showing that Desired Capacity is set to 12.

And in the Capacity Reservation screen we can see that all our On Demand Capacity Reservations have been used up:

Listing of consumed Capacity Reservations across the three Availability Zones, showing that all nine On Demand Capacity Reservations are used.

In the Auto Scaling Group we see that – as expected – we weren’t restricted to nine instances. Instead, the Auto Scaling Group fell back on launching unreserved instances when our On Demand Capacity Reservations ran out:

Listing of Instances in the Auto Scaling Group, showing that the total count is 12.

How does the solution react to adding a matching instance outside the Auto Scaling Group?

But what if someone else/another process in the account starts an EC2 instance of the same type for which we have the On Demand Capacity Reservations? Won’t they get that Reservation, and our Auto Scaling Group will be left short of its three instances per AZ, which would mean that we won’t have enough reservations for our minimum of six instances in case there are issues with an AZ?

This all comes down to the type of On Demand Capacity Reservation that we have created, or the “Eligibility”. Looking at our Capacity Reservations, we can see that they are all of the “targeted” type. This means that they are only used if explicitly referenced, like we’re doing in our Target Group for the Auto Scaling Group.

Listing of existing Capacity Reservations, showing that they are of the targeted type.

It’s time to prove that. First, we scale in our Auto Scaling Group so that only six instances are used, resulting in there being one unused capacity reservation in each AZ. Then, we try to add an EC2 instance manually, outside the target group.

First, scale in the Auto Scaling Group:

aws autoscaling set-desired-capacity \
--auto-scaling-group-name $AUTOSCALING_GROUP_NAME \
--desired-capacity 6

Listing of consumed Capacity Reservations across the three Availability Zones, showing two used reservations per Availability Zone.

Listing of Instances in the Auto Scaling Group, showing that the total count is six

Then, spin up the new instance, and save its ID for later when we clean up:

export MANUALLY_CREATED_INSTANCE_ID=$(aws ec2 run-instances \
--image-id resolve:ssm:/aws/service/ami-amazon-linux-latest/amzn2-ami-hvm-x86_64-gp2 \
--instance-type t2.micro \
--subnet-id $SUBNET_FOR_MANUALLY_ADDED_INSTANCE \
--query 'Instances[0].InstanceId' --output text) 

Listing of the newly created instance, showing that it is running.

We still have the three unutilized On Demand Capacity Reservations, as expected, proving that the On Demand Capacity Reservations with the “targeted” eligibility only get used when explicitly referenced:

Listing of consumed Capacity Reservations across the three Availability Zones, showing two used reservations per Availability Zone.

How does the solution react to an AZ being removed?

Now we’re comfortable that the Auto Scaling Group can grow beyond the On Demand Capacity Reservations if needed, as long as there is capacity, and that other EC2 instances in our account won’t use the On Demand Capacity Reservations specifically purchased for the Auto Scaling Group. It’s time for the big test. How does it all behave when an AZ becomes unavailable?

For our purposes, we can simulate this scenario by changing the Auto Scaling Group to be across two AZs instead of the original three.

First, we scale out to seven instances so that we can see the impact of overflow outside the On Demand Capacity Reservations when we subsequently remove one AZ:

aws autoscaling set-desired-capacity \
--auto-scaling-group-name $AUTOSCALING_GROUP_NAME \
--desired-capacity 7

Then, we change the Auto Scaling Group to only cover two AZs:

aws autoscaling update-auto-scaling-group \
--auto-scaling-group-name $AUTOSCALING_GROUP_NAME \
--vpc-zone-identifier $SUBNETS_TO_KEEP

Give it some time, and we see that the Auto Scaling Group is now spread across two AZs, On Demand Capacity Reservations cover the minimum six instances as per our requirements, and the rest is handled by instances without Capacity Reservation:

Network details for the Auto Scaling Group, showing that it is configured for two Availability Zones.

Listing of consumed Capacity Reservations across the three Availability Zones, showing two Availability Zones using three On Demand Capacity Reservations each, with the third Availability Zone not using any of its On Demand Capacity Reservations.

Listing of Instances in the Auto Scaling Group, showing that there are 4 instances in the eu-west-2a Availability Zone.

Cleanup

It’s time to clean up, as those Instances and On Demand Capacity Reservations come at a cost!

  1. First, remove the EC2 instance that we made:
    aws ec2 terminate-instances --instance-ids $MANUALLY_CREATED_INSTANCE_ID
  2. Then, delete the CloudFormation stack.

Conclusion

Using a combination of Auto Scaling Groups, Resource Groups, and On Demand Capacity Reservations (ODCRs), we have built a solution that provides High Availability backed by reserved capacity, for those types of workloads where the requirements for availability in the case of an AZ becoming temporarily unavailable outweigh the increased cost of reserving capacity, and where the best practices for architecting for flexibility cannot be followed due to limitations on applicable architectures.

We have tested the solution and confirmed that the Auto Scaling Group falls back on using unreserved capacity when the On Demand Capacity Reservations are exhausted. Moreover, we confirmed that targeted On Demand Capacity Reservations won’t risk getting accidentally used by other solutions in our account.

Now it’s time for you to try it yourself! Download the IaC template and give it a try! And if you are planning on using On Demand Capacity Reservations, then don’t forget to look into Savings Plans, as they significantly reduce the cost of that Reserved Capacity..

Best practices to optimize your Amazon EC2 Spot Instances usage

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/best-practices-to-optimize-your-amazon-ec2-spot-instances-usage/

This blog post is written by Pranaya Anshu, EC2 PMM, and Sid Ambatipudi, EC2 Compute GTM Specialist.

Amazon EC2 Spot Instances are a powerful tool that thousands of customers use to optimize their compute costs. The National Football League (NFL) is an example of customer using Spot Instances, leveraging 4000 EC2 Spot Instances across more than 20 instance types to build its season schedule. By using Spot Instances, it saves 2 million dollars every season! Virtually any organization – small or big – can benefit from using Spot Instances by following best practices.

Overview of Spot Instances

Spot Instances let you take advantage of unused EC2 capacity in the AWS cloud and are available at up to a 90% discount compared to On-Demand prices. Through Spot Instances, you can take advantage of the massive operating scale of AWS and run hyperscale workloads at a significant cost saving. In exchange for these discounts, AWS has the option to reclaim Spot Instances when EC2 requires the capacity. AWS provides a two-minute notification before reclaiming Spot Instances, allowing workloads running on those instances to be gracefully shut down.

In this blog post, we explore four best practices that can help you optimize your Spot Instances usage and minimize the impact of Spot Instances interruptions: diversifying your instances, considering attribute-based instance type selection, leveraging Spot placement scores, and using the price-capacity-optimized allocation strategy. By applying these best practices, you’ll be able to leverage Spot Instances for appropriate workloads and ultimately reduce your compute costs. Note for the purposes of this blog, we will focus on the integration of Spot Instances with Amazon EC2 Auto Scaling groups.

Pre-requisites

Spot Instances can be used for various stateless, fault-tolerant, or flexible applications such as big data, containerized workloads, CI/CD, web servers, high-performance computing (HPC), and AI/ML workloads. However, as previously mentioned, AWS can interrupt Spot Instances with a two-minute notification, so it is best not to use Spot Instances for workloads that cannot handle individual instance interruption — that is, workloads that are inflexible, stateful, fault-intolerant, or tightly coupled.

Best practices

  1. Diversify your instances

The fundamental best practice when using Spot Instances is to be flexible. A Spot capacity pool is a set of unused EC2 instances of the same instance type (for example, m6i.large) within the same AWS Region and Availability Zone (for example, us-east-1a). When you request Spot Instances, you are requesting instances from a specific Spot capacity pool. Since Spot Instances are spare EC2 capacity, you want to base your selection (request) on as many spare pools of capacity as possible in order to increase your likelihood of getting Spot Instances. You should diversify across instance sizes, generations, instance types, and Availability Zones to maximize your savings with Spot Instances. For example, if you are currently using c5a.large in us-east-1a, consider including c6a instances (newer generation of instances), c5a.xl (larger size), or us-east-1b (different Availability Zone) to increase your overall flexibility. Instance diversification is beneficial not only for selecting Spot Instances, but also for scaling, resilience, and cost optimization.

To get hands-on experience with Spot Instances and to practice instance diversification, check out Amazon EC2 Spot Instances workshops. And once you’ve diversified your instances, you can leverage AWS Fault Injection Simulator (AWS FIS) to test your applications’ resilience to Spot Instance interruptions to ensure that they can maintain target capacity while still benefiting from the cost savings offered by Spot Instances. To learn more about stress testing your applications, check out the Back to Basics: Chaos Engineering with AWS Fault Injection Simulator video and AWS FIS documentation.

  1. Consider attribute-based instance type selection

We have established that flexibility is key when it comes to getting the most out of Spot Instances. Similarly, we have said that in order to access your desired Spot Instances capacity, you should select multiple instance types. While building and maintaining instance type configurations in a flexible way may seem daunting or time-consuming, it doesn’t have to be if you use attribute-based instance type selection. With attribute-based instance type selection, you can specify instance attributes — for example, CPU, memory, and storage — and EC2 Auto Scaling will automatically identify and launch instances that meet your defined attributes. This removes the manual-lift of configuring and updating instance types. Moreover, this selection method enables you to automatically use newly released instance types as they become available so that you can continuously have access to an increasingly broad range of Spot Instance capacity. Attribute-based instance type selection is ideal for workloads and frameworks that are instance agnostic, such as HPC and big data workloads, and can help to reduce the work involved with selecting specific instance types to meet specific requirements.

For more information on how to configure attribute-based instance selection for your EC2 Auto Scaling group, refer to Create an Auto Scaling Group Using Attribute-Based Instance Type Selection documentation. To learn more about attribute-based instance type selection, read the Attribute-Based Instance Type Selection for EC2 Auto Scaling and EC2 Fleet news blog or check out the Using Attribute-Based Instance Type Selection and Mixed Instance Groups section of the Launching Spot Instances workshop.

  1. Leverage Spot placement scores

Now that we’ve stressed the importance of flexibility when it comes to Spot Instances and covered the best way to select instances, let’s dive into how to find preferred times and locations to launch Spot Instances. Because Spot Instances are unused EC2 capacity, Spot Instances capacity fluctuates. Correspondingly, it is possible that you won’t always get the exact capacity at a specific time that you need through Spot Instances. Spot placement scores are a feature of Spot Instances that indicates how likely it is that you will be able to get the Spot capacity that you require in a specific Region or Availability Zone. Your Spot placement score can help you reduce Spot Instance interruptions, acquire greater capacity, and identify optimal configurations to run workloads on Spot Instances. However, it is important to note that Spot placement scores serve only as point-in-time recommendations (scores can vary depending on current capacity) and do not provide any guarantees in terms of available capacity or risk of interruption.  To learn more about how Spot placement scores work and to get started with them, see the Identifying Optimal Locations for Flexible Workloads With Spot Placement Score blog and Spot placement scores documentation.

As a near real-time tool, Spot placement scores are often integrated into deployment automation. However, because of its logging and graphic capabilities, you may find it to be a valuable resource even before you launch a workload in the cloud. If you are looking to understand historical Spot placement scores for your workload, you should check out the Spot placement score tracker, a tool that automates the capture of Spot placement scores and stores Spot placement score metrics in Amazon CloudWatch. The tracker is available through AWS Labs, a GitHub repository hosting tools. Learn more about the tracker through the Optimizing Amazon EC2 Spot Instances with Spot Placement Scores blog.

When considering ideal times to launch Spot Instances and exploring different options via Spot placement scores, be sure to consider running Spot Instances at off-peak hours – or hours when there is less demand for EC2 Instances. As you may assume, there is less unused capacity – Spot Instances – available during typical business hours than after business hours. So, in order to leverage as much Spot capacity as you can, explore the possibility of running your workload at hours when there is reduced demand for EC2 instances and thus greater availability of Spot Instances. Similarly, consider running your Spot Instances in “off-peak Regions” – or Regions that are not experiencing business hours at that certain time.

On a related note, to maximize your usage of Spot Instances, you should consider using previous generation of instances if they meet your workload needs. This is because, as with off-peak vs peak hours, there is typically greater capacity available for previous generation instances than current generation instances, as most people tend to use current generation instances for their compute needs.

  1. Use the price-capacity-optimized allocation strategy

Once you’ve selected a diversified and flexible set of instances, you should select your allocation strategy. When launching instances, your Auto Scaling group uses the allocation strategy that you specify to pick the specific Spot pools from all your possible pools. Spot offers four allocation strategies: price-capacity-optimized, capacity-optimized, capacity-optimized-prioritized, and lowest-price. Each of these allocation strategies select Spot Instances in pools based on price, capacity, a prioritized list of instances, or a combination of these factors.

The price-capacity-optimized strategy launched in November 2022. This strategy makes Spot Instance allocation decisions based on the most capacity at the lowest price. It essentially enables Auto Scaling groups to identify the Spot pools with the highest capacity availability for the number of instances that are launching. In other words, if you select this allocation strategy, we will find the Spot capacity pools that we believe have the lowest chance of interruption in the near term. Your Auto Scaling groups then request Spot Instances from the lowest priced of these pools.

We recommend you leverage the price-capacity-optimized allocation strategy for the majority of your workloads that run on Spot Instances. To see how the price-capacity-optimized allocation strategy selects Spot Instances in comparison with lowest-price and capacity-optimized allocation strategies, read the Introducing the Price-Capacity-Optimized Allocation Strategy for EC2 Spot Instances blog post.

Clean-up

If you’ve explored the different Spot Instances workshops we recommended throughout this blog post and spun up resources, please remember to delete resources that you are no longer using to avoid incurring future costs.

Conclusion

Spot Instances can be leveraged to reduce costs across a wide-variety of use cases, including containers, big data, machine learning, HPC, and CI/CD workloads. In this blog, we discussed four Spot Instances best practices that can help you optimize your Spot Instance usage to maximize savings: diversifying your instances, considering attribute-based instance type selection, leveraging Spot placement scores, and using the price-capacity-optimized allocation strategy.

To learn more about Spot Instances, check out Spot Instances getting started resources. Or to learn of other ways of reducing costs and improving performance, including leveraging other flexible purchase models such as AWS Savings Plans, read the Increase Your Application Performance at Lower Costs eBook or watch the Seven Steps to Lower Costs While Improving Application Performance webinar.

AWS Nitro System gets independent affirmation of its confidential compute capabilities

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/aws-nitro-system-gets-independent-affirmation-of-its-confidential-compute-capabilities/

This blog post was written By Anthony Liguori, VP/Distinguished Engineer, EC2 AWS.

Customers around the world trust AWS to keep their data safe, and keeping their workloads secure and confidential is foundational to how we operate. Since the inception of AWS, we have relentlessly innovated on security, privacy tools, and practices to meet, and even exceed, our customers’ expectations.

The AWS Nitro System is the underlying platform for all modern AWS compute instances which has allowed us to deliver the data isolation, performance, cost, and pace of innovation that our customers require. It’s a pioneering design of specialized hardware and software that protects customer code and data from unauthorized access during processing.

When we launched the Nitro System in 2017, we delivered a unique architecture that restricts any operator access to customer data. This means no person or even service from AWS, can access data when it is being used in an Amazon EC2 instance. We knew that designing the system this way would present several architectural and operational challenges for us. However, we also knew that protecting customers’ data in this way was the best way to support our customer’s needs.

When AWS made its Digital Sovereignty Pledge last year, we committed to providing greater transparency and assurances to customers about how AWS services are designed and operated, especially when it comes to handling customer data. As part of that increased transparency, we engaged NCC Group, a leading cybersecurity consulting firm based in the United Kingdom, to conduct an independent architecture review of the Nitro System and the security assurances we make to our customers. NCC has now issued its rand affirmed our claims.

The report states, “As a matter of design, NCC Group found no gaps in the Nitro System that would compromise [AWS] security claims.” Specifically, the report validates the following statements about our Nitro System production hosts:

  1. There is no mechanism for a cloud service provider employee to log in to the underlying host.
  2. No administrative API can access customer content on the underlying host.
  3. There is no mechanism for a cloud service provider employee to access customer content stored on instance storage and encrypted EBS volumes.
  4. There is no mechanism for a cloud service provider employee to access encrypted data transmitted over the network.
  5. Access to administrative APIs always requires authentication and authorization.
  6. Access to administrative APIs is always logged.
  7. Hosts can only run tested and signed software that is deployed by an authenticated and authorized deployment service. No cloud service provider employee can deploy code directly onto hosts.

The report details NCC’s analysis for each of these claims. You can also find additional details about the scope, methodology, and steps that NCC used to evaluate the claims.

How Nitro System protects customer data

At AWS, we know that our customers, especially those who have sensitive or confidential data, may have worries about putting that data in the cloud. That’s why we’ve architected the Nitro System to ensure that your confidential information is as secure as possible. We do this in several ways:

There is no mechanism for any system or person to log in to Amazon EC2 servers, read the memory of EC2 instances, or access any data on encrypted Amazon Elastic Block Store (EBS) volumes.

If any AWS operator, including those with the highest privileges, needs to perform maintenance work on the EC2 server, they can do so only by using a strictly limited set of authenticated, authorized, and audited administrative APIs. Critically, none of these APIs have the ability to access customer data on the EC2 server. These restrictions are built into the Nitro System itself, and no AWS operator can circumvent these controls and protections.

The Nitro System also protects customers from AWS system software through the innovative design of our lightweight Nitro Hypervisor, which manages memory and CPU allocation. Typical commercial hypervisors provide administrators with full access to the system, but with the Nitro System, the only interface operators can use is a restricted API. This means that customers and operators cannot interact with the system in unapproved ways and there is no equivalent of a “root” user. This approach enhances security and allows AWS to update systems in the background, fix system bugs, monitor performance, and even perform upgrades without impacting customer operations or customer data. Customers are unaffected during system upgrades, and their data remains protected.

Finally, the Nitro System can also provide customers an extra layer of data isolation from their own operators and software. AWS created  , which allow for isolated compute environments, which is ideal for organizations that need to process personally identifiable information, as well as healthcare, financial, and intellectual property data within their compute instances. These enclaves do not share memory or CPU cores with the customer instance. Further, Nitro Enclaves have cryptographic attestation capabilities that let customers verify that all of the software deployed has been validated and not compromised.

All of these prongs of the Nitro System’s security and confidential compute capabilities required AWS to invest time and resources into building the system’s architecture. We did so because we wanted to ensure that our customers felt confident entrusting us with their most sensitive and confidential data, and we have worked to continue earning that trust. We are not done and this is just one step AWS is taking to increase the transparency about how our services are designed and operated. We will continue to innovate on and deliver unique features that further enhance our customers’ security without compromising on performance.

Learn more:

Watch Anthony speak about AWS Nitro System Security here.

Build efficient, cross-Regional, I/O-intensive workloads with Dask on AWS

Post Syndicated from Patrick O'Connor original https://aws.amazon.com/blogs/big-data/build-efficient-cross-regional-i-o-intensive-workloads-with-dask-on-aws/

Welcome to the era of data. The sheer volume of data captured daily continues to grow, calling for platforms and solutions to evolve. Services such as Amazon Simple Storage Service (Amazon S3) offer a scalable solution that adapts yet remains cost-effective for growing datasets. The Amazon Sustainability Data Initiative (ASDI) uses the capabilities of Amazon S3 to provide a no-cost solution for you to store and share climate science workloads across the globe. Amazon’s Open Data Sponsorship Program allows organizations to host free of charge on AWS.

Over the last decade, we’ve seen a surge in data science frameworks coming to fruition, along with mass adoption by the data science community. One such framework is Dask, which is powerful for its ability to provision an orchestration of worker compute nodes, thereby accelerating complex analysis on large datasets.

In this post, we show you how to deploy a custom AWS Cloud Development Kit (AWS CDK) solution that extends Dask’s functionality to work inter-Regionally across Amazon’s global network. The AWS CDK solution deploys a network of Dask workers across two AWS Regions, connecting into a client Region. For more information, refer to Guidance for Distributed Computing with Cross Regional Dask on AWS and the GitHub repo for open-source code.

After deployment, the user will have access to a Jupyter notebook, where they can interact with two datasets from ASDI on AWS: Coupled Model Intercomparison Project 6 (CMIP6) and ECMWF ERA5 Reanalysis. CMIP6 focuses on the sixth phase of global coupled ocean-atmosphere general circulation model ensemble; ERA5 is the fifth generation of ECMWF atmospheric reanalyses of the global climate, and the first reanalysis produced as an operational service.

This solution was inspired by work with a key AWS customer, the UK Met Office. The Met Office was founded in 1854 and is the national meteorological service for the UK. They provide weather and climate predictions to help you make better decisions to stay safe and thrive. A collaboration between the Met Office and EUMETSAT, detailed in Data Proximate Computation on a Dask Cluster Distributed Between Data Centres, highlights the growing need to develop a sustainable, efficient, and scalable data science solution. This solution achieves this by bringing compute closer to the data, rather than forcing the data to come closer to compute resources, which adds cost, latency, and energy.

Solution overview

Each day, the UK Met Office produces up to 300 TB of weather and climate data, a portion of which is published to ASDI. These datasets are distributed across the world and hosted for public use. The Met Office would like to enable consumers to make the more of their data to help inform critical decisions on addressing issues such as better preparation for climate change-induced wildfires and floods, and reducing food insecurity through better crop yield analysis.

Traditional solutions in use today, particularly with climate data, are time consuming and unsustainable, replicating datasets cross Regions. Unnecessary data transfer on the petabyte scale is costly, slow, and consumes energy.

We estimated that if this practice were adopted by the Met Office users, the equivalent of 40 homes’ daily power consumption could be saved every day, and they could also reduce the transfer of data between regions.

The following diagram illustrates the solution architecture.

The solution can be broken into three major segments: client, workers, and network. Let’s dive into each and see how they come together.

Client

The client represents the source Region where data scientists connect. This Region (Region A in the diagram) contains an Amazon SageMaker notebook, an Amazon OpenSearch Service domain, and a Dask scheduler as key components. System administrators have access to the built-in Dask dashboard exposed via an Elastic Load Balancer.

Data scientists have access to the Jupyter notebook hosted on SageMaker. The notebook is able to connect and run workloads on the Dask scheduler. The OpenSearch Service domain stores metadata on the datasets connected at the Regions. Notebook users can query this service to retrieve details such as the correct Region of Dask workers without needing to know the data’s Regional location beforehand.

Worker

Each of the worker Regions (Regions B and C in the diagram) is comprised of an Amazon Elastic Container Service (Amazon ECS) cluster of Dask workers, an Amazon FSx for Lustre file system, and a standalone Amazon Elastic Compute Cloud (Amazon EC2) instance. FSx for Lustre allows Dask workers to access and process Amazon S3 data from a high-performance file system by linking your file systems to S3 buckets. It provides sub-millisecond latencies, up to hundreds of GBs/s of throughput, and millions of IOPS. A key feature of Lustre is that only the file system’s metadata is synced. Lustre manages the balance of files to be loaded in and kept warm, based on demand.

Worker clusters scale based on CPU usage, provision additional workers in extended periods of demand, and scale down as resources become idle.

Each night at 0:00 UTC, a data sync job prompts the Lustre file system to resync with the attached S3 bucket, and pulls an up-to-date metadata catalog of the bucket. Subsequently, the standalone EC2 instance pushes these updates into OpenSearch Service respective to that Region’s index. OpenSearch Service provides the necessary information to the client as to which pool of workers should be called upon for a particular dataset.

Network

Networking forms the crux of this solution, utilizing Amazon’s internal backbone network. By using AWS Transit Gateway, we’re able to connect each of the Regions to each other without needing to traverse the public internet. Each of the workers are able to connect dynamically into the Dask scheduler, allowing data scientists to run inter-regional queries through Dask.

Prerequisites

The AWS CDK package uses the TypeScript programming language. Follow the steps in Getting Started for AWS CDK to set up your local environment and bootstrap your development account (you’ll need to bootstrap all Regions specified in the GitHub repo).

For a successful deployment, you’ll need Docker installed and running on your local machine.

Deploy the AWS CDK package

Deploying an AWS CDK package is straightforward. After you install the prerequisites and bootstrap your account, you can proceed with downloading the code base.

  1. Download the GitHub repository:
    # Command to clone the repository
    git clone https://github.com/aws-solutions-library-samples/distributed-compute-on-aws-with-cross-regional-dask.git
    cd distributed-compute-on-aws-with-cross-regional-dask

  2. Install node modules:
    npm install

  3. Deploy the AWS CDK:
    npx cdk deploy --all

The stack can take over an hour and a half to deploy.

Code walkthrough

In this section, we inspect some of the key features of the code base. If you’d like to inspect the full code base, refer to the GitHub repository.

Configure and customize your stack

In the file bin/variables.ts, you’ll find two variable declarations: one for the client and one for workers. The client declaration is a dictionary with a reference to a Region and CIDR range. Customizing these variables will change both the Region and CIDR range of where client resources will deploy.

The worker variable copies this same functionality; however, it’s a list of dictionaries to accommodate adding or subtracting datasets the user wishes to include. Additionally, each dictionary contains the added fields of dataset and lustreFileSystemPath. Dataset is used to specify the connecting S3 URI for Lustre to connect to. The lustreFileSystemPath variable is used as a mapping for how the user wants that dataset to map locally on the worker file system. See the following code:

export const client: IClient = { region: "eu-west-2", cidr: "10.0.0.0/16" };

export const workers: IWorker[] = [
  {
    region: "us-east-1",
    cidr: "10.1.0.0/16",
    // The public s3 dataset on https://registry.opendata.aws/ you wish to connect to
    dataset: "s3://era5-pds",
    lustreFileSystemPath: "era5-pds",
  },
...]

Dynamically publish the scheduler IP

A challenge inherent to the cross-Regional nature of this project was maintaining a dynamic connection between the Dask workers and the scheduler. How could we publish an IP address, which is capable of changing, across AWS Regions? We were able to accomplish this through the use of AWS Cloud Map and associate-vpc-with-hosted-zone. The service abstracts allowing AWS to manage this DNS namespace privately. See the following code:

    /**
     * Below we initialise a private namespace which will keep track of the changing schedulers IP
     * The workers will need this IP to connect to, so instead of tracking it statically, they can
     * Simply reference the DNS which will resolve to the IP every time
     */
    const PrivateNP = new PrivateDnsNamespace(this, "local-dask", {
      name: "local-dask",
      vpc: this.vpc,
    });
    // Other regions will have to associate-vpc-with-hosted-zone to access this namespace
    new StringParameter(this, "PrivateNP Param", {
      parameterName: `privatenp-hostedid-param-${this.region}`,
      stringValue: PrivateNP.namespaceHostedZoneId,
    });
    this.schedulerDisovery = new Service(this, "Scheduler Discovery", {
      name: "Dask-Scheduler",
      namespace: PrivateNP,
    });

Jupyter notebook UI

The Jupyter notebook hosted on SageMaker provides scientists with a ready-made environment for deployment to easily connect and experiment on the loaded datasets. We used a lifecycle configuration script to provision the notebook with a preconfigured developer environment and example code base. See the following code:

  // The Sagemaker Notebook
  new CfnNotebookInstance(this, "Dask Notebook", {
    notebookInstanceName: "Dask-Notebook",
    rootAccess: "Disabled",
    directInternetAccess: "Disabled",
    defaultCodeRepository: repo.repositoryCloneUrlHttp,
    instanceType: "ml.t3.2xlarge",
    roleArn: role.roleArn,
    subnetId: this.vpc.privateSubnets[0].subnetId,
    securityGroupIds: [SagemakerSec.securityGroupId],
    lifecycleConfigName: lifecycle.notebookInstanceLifecycleConfigName,
    kmsKeyId: nbKey.keyId,
    platformIdentifier: "notebook-al2-v1",
    volumeSizeInGb: 50,
  });

Dask worker nodes

When it comes to the Dask workers, greater customizability is provided, more specifically on instance type, threads per container, and scaling alarms. By default, the workers provision on instance type m5d.4xlarge, mount to the Lustre file system on launch, and subdivide its workers and threads dynamically to ports. All this is optionally customizable. See the following code:

capacity: {
  instanceType: new InstanceType("m5d.4xlarge"),
  minCapacity: 0,
  maxCapacity: 12,
  vpcSubnets: {
    subnetType: SubnetType.PRIVATE_WITH_EGRESS,
  },
},

command: [
  "bin/sh",
  "-c",
  `pip3 install --upgrade xarray[complete] intake_esm s3fs eccodes git+https://github.com/gjoseph92/dask-worker-pools.git@main && dask worker Dask-Scheduler.local-dask:8786 --worker-port 9000:${
    9000 + NWORKERS - 1
  } --nanny-port ${9000 + NWORKERS}:${
    9000 + NWORKERS * 2 - 1
  } --resources pool-${
    this.region
  }=1 --nworkers ${NWORKERS} --nthreads ${THREADS} --no-dashboard`,
],

Performance

To assess performance, we use a sample computation and plotting of air temperature at 2 meters based on the difference between CMIP6 prediction for a month and ERA5 mean air temperature for 10 years. We set a benchmark of two workers in each Region and assess the difference in time reduction as additional workers were added. In theory, as the solution scales, there should be a productive material difference in reducing overall time.

The following table summarizes our dataset details.

Dataset Variables Disk Size Xarray Dataset Size Region
ERA5 2011–2020 (120 netcdf files) 53.5GB 364.1 GB us-east-1
CMIP6
variable_ids = ['tas'] # tas is air temperature at 2m above surface
table_id = 'Amon' # Monthly data from Atmosphere 
grid = 'gn' 
experiment_id = 'ssp245' 
activity_ids = ['ScenarioMIP', 'CMIP'] 
institution_id = 'MOHC'

1.13GB 0.11 GB us-west-2

The following table shows the results collected, showcasing the time (in seconds) for each computation and prediction in three stages in computing CMIP6 prediction, ERA5, and difference.

. . Number of Workers
Compute Region 2(CMIP) + 2(ERA) 2(CMIP) + 4(ERA) 2(CMIP) + 8(ERA)

2(CMIP)

+ 12(ERA)

CMIP6 (predicted_tas_regridded) us-west-2 11.8 11.5 11.2 11.6
ERA5 (historic_temp_regridded) us-east-1 1512 711 427 202
Difference (propogated pool) us-west-2 and us-east-1 1527 906 469 251

The following graph visualizes the performance and scale.

From our experiment, we observed a linear improvement on computation for the ERA5 dataset as the number of workers increased. As the numbers of workers increased, computation times were at times halved.

Jupyter notebook

As part of the solution launch, we deploy a preconfigured Jupyter notebook to help test the cross-Regional Dask solution. The notebook demonstrates the removed worry of needing to know the Regional location of datasets, instead querying a catalog through a series of Jupyter notebooks running in the background.

To get started, follow the instructions in this section.

The code for the notebooks can be found in lib/SagemakerCode with the primary notebook being ux_notebook.ipynb. This notebook calls upon other notebooks, triggering helper scripts. ux_notebook is designed to be the entry point for scientists, without the need for going elsewhere.

To get started, open this notebook in SageMaker after you have deployed the AWS CDK. The AWS CDK creates a notebook instance with all of the files in the repository loaded and backed up to an AWS CodeCommit repository.

To run the application, open and run the first cell of ux_notebook. This cell runs the get_variables notebook in the background, which prompts you for an input for the data you would like to select. We include an example; however, note that questions will only appear after the previous option has been selected. This is intentional in limiting the drop-down choices and is optionally configurable by editing the get_variables notebook.

The preceding code stores variables globally so that other notebooks can retrieve and load your selection of choices. For demonstration, the next cell should output the save variables from before.

Next, a prompt for further data specifications appears. This cell refines the data you’re after by presenting the IDs of tables in human-readable format. Users select as if it were a form, but the titles map to tables in the background that help the system retrieve the appropriate datasets.

After you have stored all your choices and selection cells, load the data into the Regions by running the cell in the Getting the data set section. The %%capture command will suppress unnecessary outputs from the get_data notebook. Note you may remove this to inspect outputs from the other notebooks. Data is then retrieved in the backend.

While other notebooks are being run in the background, the only touchpoint for the user is the ux_notebook. This is to abstract the tedious process of importing data into a format any user is able to follow with ease.

With the data now loaded, we can start interacting with it. The following cells are examples of calculations you may run on weather data. Using xarrays, we import, calculate, and then plot those datasets.

Our sample illustrates a plot of predictive data retrieving data, running the computation, and plotting the results in under 7.5 seconds—orders of magnitude faster than a typical approach.

Under the hood

The notebooks get_catalog_input and get_variables use the library ipywidgets to display widgets such as drop-downs and multi-box selections. These options are saved globally using the %%store command so that they can be accessed from the ux_notebook. One of the options prompts you on whether you want historical data, predictive data, or both. This variable is passed to the get_data notebook to determine which subsequent notebooks to run.

The get_data notebook first retrieves the shared OpenSearch Service domain saved to AWS Systems Manager Parameter Store. This domain allows our notebook to run a query on collecting information that will indicate where the selected datasets are stored Regionally. With those datasets located Regionally, the notebook will make a connection attempt to the Dask scheduler, passing the information collected from OpenSearch Service. The Dask scheduler in turn will be able to call on workers in the correct Regions.

How to customize and continue development

These notebooks are meant to be an example of how you can create a way for users to interface and interact with the data. The notebook in this post serves as an illustration for what’s possible, and we invite you to continue building upon the solution to further improve user engagement. The core part of this solution is the backend technology, but without some mechanism to interact with that backend, users won’t realize the full potential of the solution.

Clean up

To avoid incurring future charges, delete the resources. Let’s destroy our deployed solution with the following command:

npx cdk destroy –all

Conclusion

This post showcases the extension of Dask inter-Regionally on AWS, and a possible integration with public datasets on AWS. The solution was built as a generic pattern, and further datasets can be loaded in to accelerate high I/O analyses on complex data.

Data is transforming every field and every business. However, with data growing faster than most companies can keep track of, collecting data and getting value out of that data is challenging. A modern data strategy can help you create better business outcomes with data. AWS provides the most complete set of services for the end-to-end data journey to help you unlock value from your data and turn it into insight.

To learn more about the various ways to use your data on the cloud, visit the AWS Big Data Blog. We further invite you to comment with your thoughts on this post, and whether this is a solution you plan on trying out.


About the Authors

 Patrick O’Connor is a WWSO Prototyping Engineer based in London. He is a creative problem-solver, adaptable across a wide range of technologies, such as IoT, serverless tech, 3D spatial tech, and ML/AI, along with a relentless curiosity on how technology can continue to evolve everyday approaches.

Chakra Nagarajan is a Principal Machine Learning Prototyping SA with 21 years of experience in machine learning, big data, and high-performance computing. In his current role, he helps customers solve real-world complex business problems by building prototypes with end-to-end AI/ML solutions in cloud and edge devices. His ML specialization includes computer vision, natural language processing, time series forecasting, and personalization.

Val Cohen is a senior WWSO Prototyping Engineer based in London. A problem solver by nature, Val enjoys writing code to automate processes, build customer obsessed tools, and create infrastructure for various applications for her global customer base. Val has experience across a wide variety of technologies, such as front-end web development, backend work, and AI/ML.

Niall Robinson is Head of product futures at the UK Met Office. He and his team explore new ways the Met Office can provide value through product innovation and strategic partnerships. He’s had a varied career, leading a multidisciplinary informatics R&D team, academic research in data science, and field scientist along with climate modeler expertise.
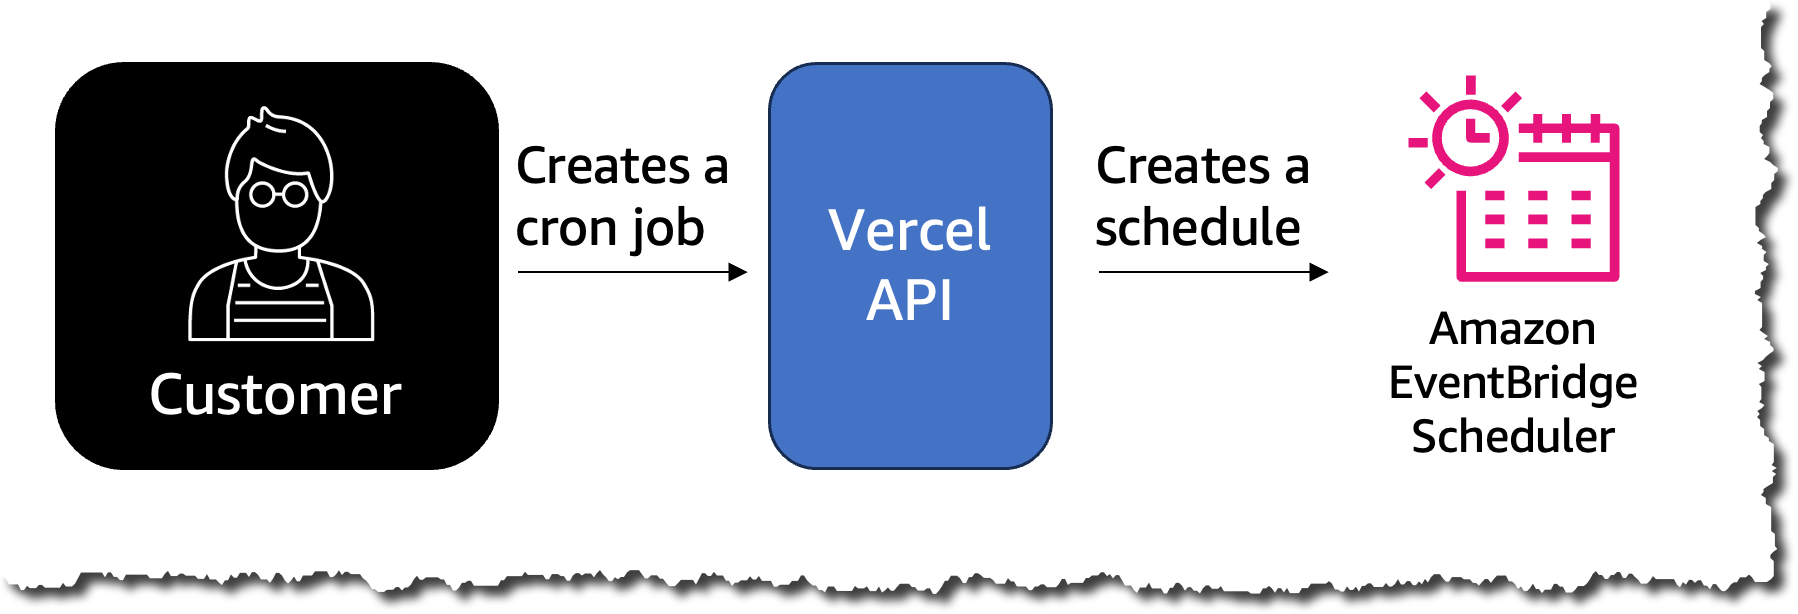
Best Practices for managing data residency in AWS Local Zones using landing zone controls

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/best-practices-for-managing-data-residency-in-aws-local-zones-using-landing-zone-controls/

This blog post is written by Abeer Naffa’, Sr. Solutions Architect, Solutions Builder AWS, David Filiatrault, Principal Security Consultant, and Jared Thompson Hybrid Edge SA Specialist.

In this post, we discuss how you can leverage AWS Control Tower landing zone and AWS Organizations custom policies – guardrails – at the root level, known as Service Control Policies (SCPS) to enable certain data residency requirements on AWS Local Zones. Using the suggested controls lets you limit the ability to store data, process data outside a geographic location, and keep your data within specific Local Zone(s).

Data residency is a critical consideration for organizations that collect and store sensitive information, such as Personal Identifiable Information (PII), financial data, and healthcare data. With the rise of cloud computing and the global nature of the Internet, it can be challenging for organizations to make sure that their data is being stored and processed in compliance with local laws and regulations.

One potential solution for addressing data residency challenges with AWS is utilizing Local Zones, which places AWS infrastructure in large metro areas. This enables organizations to store and process data in specific geographic locations. By using Local Zones, organizations can architect their environment to meet data residency requirements when an AWS Region is unavailable within the same legal jurisdiction. Local Zones can be configured to utilize landing zone to further adhere to data residency requirements.

A landing zone is a well-architected, multi-account AWS environment that is scalable and secure. This is a starting point from which your organization can quickly launch and deploy workloads and applications with confidence in your security and infrastructure environment.

When leveraging a Local Zone to meet data residency requirements, you must have control over the in-scope data movement from the Local Zones to the AWS Region. This can be accomplished by implementing landing zone best practices and the suggested guardrails. The main focus of this post is the custom policies that restrict data snapshots, prohibit data creation within the Region, and limit data transfer to the Region. Furthermore, this post covers which prerequisites organizations should consider before implementing these guardrails.

Prerequisites

Landing zones best practices and custom guardrails can help when data must remain in a specific locality where the Local Zone is also located. This can be completed by defining and enforcing policies for data storage and usage within the landing zone organization that you set up. The following prerequisites should be considered before implementing the suggested guardrails:

  1. AWS Local Zones

Local Zones are enabled through the Amazon Elastic Compute Cloud (Amazon EC2) console or the AWS Command Line Interface (AWS CLI).

You can start using available AWS services on the designated Local Zone directly from the console. Moreover, you can manage the Local Zone using the same tools and interfaces that you use in AWS Region.

2. AWS Control Tower landing zone

AWS Control Tower is a managed service that provides a pre-packaged set of best-practice blueprints for setting up and governing multi-account AWS environments. You must have Control Tower fully implemented in your environment before you can deploy custom guardrails.

Control Tower launches a key resource associated with your account, called a landing zone, which serves as a home for your organizations and their accounts.

Note that Control Tower relies on Organizations to create and manage multi-account structures.

  1. Set up the data residency guardrails

Using Organizations, you must make sure that the Local Zone is enabled within a workload account in the landing zones.

Figure 1 Landing Zones Accelerator Local Zones workload on AWS high level Architecture

Figure 1: Landing Zones Accelerator – Local Zones workload on AWS high level Architecture

Utilizing Local Zones for regulated components

The availability of Local Zones provides an excellent opportunity to meet data residency requirements and comply with local regulations that restrict the use of the Region outside of your required geo-political boundary. By leveraging Local Zones, organizations can maintain compliance while utilizing AWS services to support their business needs. AWS owns and manages the infrastructure, including hardware, software, and networking for Local Zones. However, as part of the shared responsibility model, customers are responsible for the security of their applications and data, including access control, data encryption, etc.

You must also comply with all applicable regulations and security standards, such as HIPAA, PCI DSS, and GDPR. You should conduct regular security assessments and implement appropriate security controls to protect their applications and data.

In this post, we consider a scenario where there is a single Local Zones location in a metro. However, you must analyze the specific requirements of your workloads and the relevant regulations that apply to determine the most appropriate high availability configurations for your case.

Local Zones workload data residency guardrails

Organizations provides central governance and management for multiple accounts. Central security administrators use SCPs with Organizations to establish controls to which all AWS Identity and Access Management (IAM) principals (users and roles) adhere.

Now you can use SCPs to set permission guardrails. The suggested preventative controls that leverage the implementation of SCPs for data residency on Local Zones are shown in the next paragraph. SCPs let you set permission guardrails by defining the maximum available permissions for IAM entities in an account and all accounts within the Organization root or Organizational Unit (OU). If an SCP denies an action for an account, then none of the entities in any member account, including the member account’s root user, can take that action, even if their IAM permissions let them. The guardrails set in SCPs apply to all IAM entities in the account, which include all users, roles, and the account root user.

 Upon finalizing these prerequisites, you can create the guardrails for the chosen OU.

Note that although the following guidelines serve as helpful guardrails – SCPs – for data residency, you should consult internally with legal and security teams for specific organizational requirements.

 To exercise better control over the workload in Local Zones and prevent data transfer from Local Zones or data storage outside of the Local Zones, consider implementing the following guardrails:

  1. When your data residency requirements require restricting data transfer/saving to the Region, consider the following guardrails:

a. Deny copying data from Local Zones to the Region for Amazon EC2), Amazon Relational Database Service (Amazon RDS), Amazon ElastiCache, and data sync “DenyCopyToRegion”.

As the available services in Local Zones can vary based on location, you must review the services available in the chosen Local Zone and Adjust the SCPs accordingly.

b. Deny Amazon Simple Storage Service (Amazon S3) put action to the Region “DenyPutObjectToRegionalBuckets”.

If your data residency requirements mandate restrictions on data storage in the Region, then consider implementing this guardrail to prevent the use of Amazon S3 in the Region.

c. If your data residency requirements mandate restrictions on data storage in the Region, then consider implementing “DenyDirectTransferToRegion”

Out of Scope is metadata such as tags or operational data such as AWS Key Management Service (AWS KMS) keys.

{
  "Version": "2012-10-17",
  "Statement": [
      {
      "Sid": "DenyCopyToRegion",
      "Action": [
        "ec2:ModifyImageAttribute",
        "ec2:CopyImage",  
        "ec2:CreateImage",
        "ec2:CreateInstanceExportTask",
        "ec2:ExportImage",
        "ec2:ImportImage",
        "ec2:ImportInstance",
        "ec2:ImportSnapshot",
        "ec2:ImportVolume",
        "rds:CreateDBSnapshot",
        "rds:CreateDBClusterSnapshot",
        "rds:ModifyDBSnapshotAttribute",
        "elasticache:CreateSnapshot",
        "elasticache:CopySnapshot",
        "datasync:Create*",
        "datasync:Update*"
      ],
      "Resource": "*",
      "Effect": "Deny"
    },
    {
      "Sid": "DenyDirectTransferToRegion",
      "Action": [
        "dynamodb:PutItem",
        "dynamodb:CreateTable",
        "ec2:CreateTrafficMirrorTarget",
        "ec2:CreateTrafficMirrorSession",
        "rds:CreateGlobalCluster",
        "es:Create*",
        "elasticfilesystem:C*",
        "elasticfilesystem:Put*",
        "storagegateway:Create*",
        "neptune-db:connect",
        "glue:CreateDevEndpoint",
        "glue:UpdateDevEndpoint",
        "datapipeline:CreatePipeline",
        "datapipeline:PutPipelineDefinition",
        "sagemaker:CreateAutoMLJob",
        "sagemaker:CreateData*",
        "sagemaker:CreateCode*",
        "sagemaker:CreateEndpoint",
        "sagemaker:CreateDomain",
        "sagemaker:CreateEdgePackagingJob",
        "sagemaker:CreateNotebookInstance",
        "sagemaker:CreateProcessingJob",
        "sagemaker:CreateModel*",
        "sagemaker:CreateTra*",
        "sagemaker:Update*",
        "redshift:CreateCluster*",
        "ses:Send*",
        "ses:Create*",
        "sqs:Create*",
        "sqs:Send*",
        "mq:Create*",
        "cloudfront:Create*",
        "cloudfront:Update*",
        "ecr:Put*",
        "ecr:Create*",
        "ecr:Upload*",
        "ram:AcceptResourceShareInvitation"
      ],
      "Resource": "*",
      "Effect": "Deny"
    },
    {
      "Sid": "DenyPutObjectToRegionalBuckets",
      "Action": [
        "s3:PutObject"
      ],
      "Resource": ["arn:aws:s3:::*"],
      "Effect": "Deny"
    }
  ]
}
  1. If your data residency requirements require limitations on data storage in the Region, then consider implementing this guardrail “DenyAllSnapshots” to restrict the use of snapshots in the Region.

Note that the following guardrail restricts the creation of snapshots on AWS Outposts as well. If you’re using Outposts in the same AWS account, then you may need to customize this guardrail to make sure that it aligns with your organization’s specific needs and requirements. For more information on data residency considerations for Outposts, please refer to Architecting for data residency with AWS Outposts rack and landing zone guardrails.

{
  "Version": "2012-10-17",
  "Statement": [

    {
      "Sid": "DenyAllSnapshots",
      "Effect":"Deny",
      "Action":[
        "ec2:CreateSnapshot",
        "ec2:CreateSnapshots",
        "ec2:CopySnapshot",
        "ec2:ModifySnapshotAttribute"
      ],
      "Resource":"arn:aws:ec2:*::snapshot/*"
    }
  ]
}
  1. This guardrail helps prevent the launch of EC2 instances or the creation of network interfaces by subnet as opposed to Local Zones You should keep data residency workloads within the Local Zones rather than the Region to make sure of better control over regulated workloads. This approach can help your organization achieve better control over data residency workloads and improve governance over your Organization.

 Make sure to update the Local Zones subnets < localzones_subnet_arns>.

{
"Version": "2012-10-17",
  "Statement":[{
    "Sid": "DenyNotLocalZonesSubnet",
    "Effect":"Deny",
    "Action": [
      "ec2:RunInstances",
      "ec2:CreateNetworkInterface"
    ],
    "Resource": [
      "arn:aws:ec2:*:*:network-interface/*"
    ],
    "Condition": {
      "ForAllValues:ArnNotEquals": {
        "ec2:Subnet": ["<localzones_subnet_arns>"]
      }
    }
  }]
}

Additional considerations

When implementing data residency guardrails on Local Zones, consider backup and disaster recovery strategies to make sure that your data is protected in the event of an outage or other unexpected events. This may include creating regular backups of your data, implementing disaster recovery plans and procedures, and using redundancy and failover systems to minimize the impact of any potential disruptions. Additionally, you should make sure that your backup and disaster recovery systems are compliant with any relevant data residency regulations and requirements. You should also test your backup and disaster recovery systems regularly to make sure that they are functioning as intended.

Additionally, the provided SCPs for Local Zones in the above example do not block the “logs:PutLogEvents”. Therefore, even if you implemented data residency guardrails on Local Zones, the application may log data to Amazon CloudWatch Logs in the Region.

Highlights

By default, application-level logs on Local Zones are not automatically sent to CloudWatch Logs in the Region. You can configure CloudWatch Logs agent on Local Zones to collect and send your application-level logs to CloudWatch Logs.

logs:PutLogEvents does transmit data to the Region, but it is not blocked by the provided SCPs, as it’s expected that most use cases still want to be able to use this logging API. However, if blocking is desired, then add the action to the first recommended guardrail. If you want specific roles to be allowed, then combine with the ArnNotLike condition example referenced in the Customization Guide.

Conclusion

The combined use of Local Zones and the suggested guardrails via Organizations policies enables you to exercise better control over the movement of the data. By creating a landing zone for your organization, you can apply SCPs to your Local Zones that will help make sure that your data remains within a specific geographic location, as required by the data residency regulations.

Note that, although custom guardrails can help you manage data residency on Local Zones, it’s critical to thoroughly review your policies, procedures, and configurations. This lets you make sure that they are compliant with all relevant data residency regulations and requirements. Regularly testing and monitoring your systems can help make sure that your data is protected and your organization stays compliant.

References